@@ -192,23 +226,69 @@ Put the models into the ComfyUI weights folder `ComfyUI/models/Fun_Models/`:
|
-
+
|
-
+
|
-
+
|
|
-
+
|
-
+
|
-
+
+ |
+
+
+
+### Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera
+
+
+
+ |
+ Pan Up
+ |
+
+ Pan Left
+ |
+
+ Pan Right
+ |
+
+ |
+
+ |
+
+
+ |
+
+
+ |
+
+ |
+ Pan Down
+ |
+
+ Pan Up + Pan Left
+ |
+
+ Pan Up + Pan Right
+ |
+
+ |
+
+ |
+
+
+ |
+
+
|
@@ -438,6 +518,16 @@ CogVideoX-Fun can be found in [Readme Train](scripts/cogvideox_fun/README_TRAIN.
## 1. Wan2.1-Fun
+V1.1:
+| Name | Storage Size | Hugging Face | Model Scope | Description |
+|------|--------------|--------------|-------------|-------------|
+| Wan2.1-Fun-V1.1-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP) | Wan2.1-Fun-V1.1-1.3B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
+| Wan2.1-Fun-V1.1-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP) | Wan2.1-Fun-V1.1-14B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
+| Wan2.1-Fun-V1.1-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control) | Wan2.1-Fun-V1.1-1.3B video control weights support various control conditions such as Canny, Depth, Pose, MLSD, etc., supports reference image + control condition-based control, and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
+| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control) | Wan2.1-Fun-V1.1-14B video control weights support various control conditions such as Canny, Depth, Pose, MLSD, etc., supports reference image + control condition-based control, and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
+| Wan2.1-Fun-V1.1-1.3B-Control-Camera | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control) | Wan2.1-Fun-V1.1-1.3B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
+| Wan2.1-Fun-V1.1-14B-Control-Camera | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control) | Wan2.1-Fun-V1.1-14B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
+
V1.0:
| Name | Storage Space | Hugging Face | Model Scope | Description |
|--|--|--|--|--|
@@ -489,6 +579,10 @@ V1.1:
- CogVideo: https://github.com/THUDM/CogVideo/
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
- Wan2.1: https://github.com/Wan-Video/Wan2.1/
+- ComfyUI-KJNodes: https://github.com/kijai/ComfyUI-KJNodes
+- ComfyUI-EasyAnimateWrapper: https://github.com/kijai/ComfyUI-EasyAnimateWrapper
+- ComfyUI-CameraCtrl-Wrapper: https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper
+- CameraCtrl: https://github.com/hehao13/CameraCtrl
# License
This project is licensed under the [Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE).
diff --git a/README_ja-JP.md b/README_ja-JP.md
index b7da81f..827b3cc 100755
--- a/README_ja-JP.md
+++ b/README_ja-JP.md
@@ -26,6 +26,7 @@ VideoX-Funはビデオ生成のパイプラインであり、AI画像やビデ
異なるプラットフォームからのクイックスタートをサポートします。詳細は[クイックスタート](#クイックスタート)を参照してください。
新機能:
+- Wan2.1-Fun-V1.1バージョンを更新:14Bと1.3BモデルのControl+参照画像モデルをサポート、カメラ制御にも対応。さらに、Inpaintモデルを再訓練し、性能が向上しました。[2025.04.25]
- Wan2.1-Fun-V1.0の更新:14Bおよび1.3BのI2V(画像からビデオ)モデルとControlモデルをサポートし、開始フレームと終了フレームの予測に対応。[2025.03.26]
- CogVideoX-Fun-V1.5の更新:I2Vモデルと関連するトレーニング・予測コードをアップロード。[2024.12.16]
- 報酬Loraのサポート:報酬逆伝播技術を使用してLoraをトレーニングし、生成された動画を最適化し、人間の好みによりよく一致させる。[詳細情報](scripts/README_TRAIN_REWARD.md)。新しいバージョンの制御モデルでは、Canny、Depth、Pose、MLSDなどの異なる制御条件に対応。[2024.11.21]
@@ -67,10 +68,10 @@ docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cud
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
# コードをクローン
-git clone https://github.com/aigc-apps/CogVideoX-Fun.git
+git clone https://github.com/aigc-apps/VideoX-Fun.git
-# CogVideoX-Funのディレクトリに入る
-cd CogVideoX-Fun
+# VideoX-Funのディレクトリに入る
+cd VideoX-Fun
# 重みをダウンロード
mkdir models/Diffusion_Transformer
@@ -82,8 +83,8 @@ mkdir models/Personalized_Model
# https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP
# Wan
-# https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP
-# https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP
+# https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP
+# https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP
```
### 2. ローカルインストール: 環境チェック/ダウンロード/インストール
@@ -119,8 +120,8 @@ Linuxの詳細:
│ └── 📂 Fun_Models/
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
-│ ├── 📂 Wan2.1-Fun-14B-InP
-│ └── 📂 Wan2.1-Fun-1.3B-InP/
+│ ├── 📂 Wan2.1-Fun-V1.1-14B-InP
+│ └── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
```
**独自のpythonファイルまたはUIインターフェースを実行**:
@@ -129,29 +130,29 @@ Linuxの詳細:
├── 📂 Diffusion_Transformer/
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
-│ ├── 📂 Wan2.1-Fun-14B-InP
-│ └── 📂 Wan2.1-Fun-1.3B-InP/
+│ ├── 📂 Wan2.1-Fun-V1.1-14B-InP
+│ └── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
├── 📂 Personalized_Model/
│ └── あなたのトレーニング済みのトランスフォーマーモデル / あなたのトレーニング済みのLoraモデル(UIロード用)
```
# ビデオ結果
-### Wan2.1-Fun-14B-InP && Wan2.1-Fun-1.3B-InP
+### Wan2.1-Fun-V1.1-14B-InP && Wan2.1-Fun-V1.1-1.3B-InP
@@ -159,22 +160,55 @@ Linuxの詳細:
-### Wan2.1-Fun-14B-Control && Wan2.1-Fun-1.3B-Control
+### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
+Generic Control Video + Reference Image:
+
+
+ |
+ Reference Image
+ |
+
+ Control Video
+ |
+
+ Wan2.1-Fun-V1.1-14B-Control
+ |
+
+ Wan2.1-Fun-V1.1-1.3B-Control
+ |
+
+ |
+
+ |
+
+
+ |
+
+
+ |
+
+
+ |
+
+
+
+
+Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
@@ -192,23 +226,69 @@ Linuxの詳細:
|
-
+
|
-
+
|
-
+
|
|
-
+
|
-
+
|
-
+
+ |
+
+
+
+### Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera
+
+
+
+ |
+ Pan Up
+ |
+
+ Pan Left
+ |
+
+ Pan Right
+ |
+
+ |
+
+ |
+
+
+ |
+
+
+ |
+
+ |
+ Pan Down
+ |
+
+ Pan Up + Pan Left
+ |
+
+ Pan Up + Pan Right
+ |
+
+ |
+
+ |
+
+
+ |
+
+
|
@@ -436,6 +516,17 @@ CogVideoX-Funは[Readme Train](scripts/cogvideox_fun/README_TRAIN.md)と[Readme
# モデルの場所
## 1. Wan2.1-Fun
+V1.1:
+| 名称 | ストレージ容量 | Hugging Face | Model Scope | 説明 |
+|--|--|--|--|--|
+| Wan2.1-Fun-V1.1-1.3B-InP | 19.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP) | Wan2.1-Fun-V1.1-1.3Bのテキスト・画像から動画生成の重み。マルチ解像度で訓練され、最初と最後の画像予測をサポートします。 |
+| Wan2.1-Fun-V1.1-14B-InP | 47.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP) | Wan2.1-Fun-V1.1-14Bのテキスト・画像から動画生成の重み。マルチ解像度で訓練され、最初と最後の画像予測をサポートします。 |
+| Wan2.1-Fun-V1.1-1.3B-Control | 19.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control)| Wan2.1-Fun-V1.1-1.3Bのビデオ制御重み。Canny、Depth、Pose、MLSDなどの異なる制御条件に対応し、参照画像+制御条件を使用した制御や軌跡制御をサポートします。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
+| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control)| Wan2.1-Fun-V1.1-14Bのビデオ制御重み。Canny、Depth、Pose、MLSDなどの異なる制御条件に対応し、参照画像+制御条件を使用した制御や軌跡制御をサポートします。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
+| Wan2.1-Fun-V1.1-1.3B-Control-Camera | 19.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control)| Wan2.1-Fun-V1.1-1.3Bのカメラレンズ制御重み。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
+| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control)| Wan2.1-Fun-V1.1-14Bのカメラレンズ制御重み。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
+
+
V1.0:
| 名称 | ストレージ容量 | Hugging Face | Model Scope | 説明 |
|--|--|--|--|--|
diff --git a/README_zh-CN.md b/README_zh-CN.md
index c54ce5f..29933c6 100755
--- a/README_zh-CN.md
+++ b/README_zh-CN.md
@@ -26,6 +26,7 @@ VideoX-Fun是一个视频生成的pipeline,可用于生成AI图片与视频、
我们会逐渐支持从不同平台快速启动,请参阅 [快速启动](#快速启动)。
新特性:
+- 更新Wan2.1-Fun-V1.1版本:支持14B与1.3B模型Control+参考图模型,支持镜头控制,另外Inpaint模型重新训练,性能更佳。[2025.04.25]
- 更新Wan2.1-Fun-V1.0版本:支持14B与1.3B模型的I2V和Control模型,支持首尾图预测。[2025.03.26]
- 更新CogVideoX-Fun-V1.5版本:上传I2V模型与相关训练预测代码。[2024.12.16]
- 奖励Lora支持:通过奖励反向传播技术训练Lora,以优化生成的视频,使其更好地与人类偏好保持一致,[更多信息](scripts/README_TRAIN_REWARD.md)。新版本的控制模型,支持不同的控制条件,如Canny、Depth、Pose、MLSD等。[2024.11.21]
@@ -65,10 +66,10 @@ docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cud
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
# clone code
-git clone https://github.com/aigc-apps/CogVideoX-Fun.git
+git clone https://github.com/aigc-apps/VideoX-Fun.git
-# enter CogVideoX-Fun's dir
-cd CogVideoX-Fun
+# enter VideoX-Fun's dir
+cd VideoX-Fun
# download weights
mkdir models/Diffusion_Transformer
@@ -80,8 +81,8 @@ mkdir models/Personalized_Model
# https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP
# Wan
-# https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP
-# https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP
+# https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP
+# https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP
```
### 2. 本地安装: 环境检查/下载/安装
@@ -117,8 +118,8 @@ Linux 的详细信息:
│ └── 📂 Fun_Models/
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
-│ ├── 📂 Wan2.1-Fun-14B-InP
-│ └── 📂 Wan2.1-Fun-1.3B-InP/
+│ ├── 📂 Wan2.1-Fun-V1.1-14B-InP
+│ └── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
```
**运行自身的python文件或ui界面**:
@@ -127,29 +128,29 @@ Linux 的详细信息:
├── 📂 Diffusion_Transformer/
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
-│ ├── 📂 Wan2.1-Fun-14B-InP
-│ └── 📂 Wan2.1-Fun-1.3B-InP/
+│ ├── 📂 Wan2.1-Fun-V1.1-14B-InP
+│ └── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
├── 📂 Personalized_Model/
│ └── your trained trainformer model / your trained lora model (for UI load)
```
# 视频作品
-### Wan2.1-Fun-14B-InP && Wan2.1-Fun-1.3B-InP
+### Wan2.1-Fun-V1.1-14B-InP && Wan2.1-Fun-V1.1-1.3B-InP
@@ -157,22 +158,55 @@ Linux 的详细信息:
-### Wan2.1-Fun-14B-Control && Wan2.1-Fun-1.3B-Control
+### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
+Generic Control Video + Reference Image:
+
+
+ |
+ Reference Image
+ |
+
+ Control Video
+ |
+
+ Wan2.1-Fun-V1.1-14B-Control
+ |
+
+ Wan2.1-Fun-V1.1-1.3B-Control
+ |
+
+ |
+
+ |
+
+
+ |
+
+
+ |
+
+
+ |
+
+
+
+
+Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
@@ -190,23 +224,69 @@ Linux 的详细信息:
|
-
+
|
-
+
|
-
+
|
|
-
+
|
-
+
|
-
+
+ |
+
+
+
+### Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera
+
+
+
+ |
+ Pan Up
+ |
+
+ Pan Left
+ |
+
+ Pan Right
+ |
+
+ |
+
+ |
+
+
+ |
+
+
+ |
+
+ |
+ Pan Down
+ |
+
+ Pan Up + Pan Left
+ |
+
+ Pan Up + Pan Right
+ |
+
+ |
+
+ |
+
+
+ |
+
+
|
@@ -433,6 +513,16 @@ CogVideoX-Fun可以查看[Readme Train](scripts/cogvideox_fun/README_TRAIN.md)
# 模型地址
## 1. Wan2.1-Fun
+V1.1:
+| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
+|--|--|--|--|--|
+| Wan2.1-Fun-V1.1-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP) | Wan2.1-Fun-V1.1-1.3B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
+| Wan2.1-Fun-V1.1-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP) | Wan2.1-Fun-V1.1-14B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
+| Wan2.1-Fun-V1.1-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control)| Wan2.1-Fun-V1.1-1.3B视频控制权重支持不同的控制条件,如Canny、Depth、Pose、MLSD等,支持参考图 + 控制条件进行控制,支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,支持多分辨率(512,768,1024)的视频预测,以81帧、每秒16帧进行训练,支持多语言预测 |
+| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control)| Wan2.1-Fun-V1.1-14B视视频控制权重支持不同的控制条件,如Canny、Depth、Pose、MLSD等,支持参考图 + 控制条件进行控制,支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,支持多分辨率(512,768,1024)的视频预测,以81帧、每秒16帧进行训练,支持多语言预测 |
+| Wan2.1-Fun-V1.1-1.3B-Control-Camera | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control)| Wan2.1-Fun-V1.1-1.3B相机镜头控制权重。支持多分辨率(512,768,1024)的视频预测,支持多分辨率(512,768,1024)的视频预测,以81帧、每秒16帧进行训练,支持多语言预测 |
+| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control)| Wan2.1-Fun-V1.1-14B相机镜头控制权重。支持多分辨率(512,768,1024)的视频预测,支持多分辨率(512,768,1024)的视频预测,以81帧、每秒16帧进行训练,支持多语言预测 |
+
V1.0:
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|--|--|--|--|--|
@@ -485,6 +575,10 @@ V1.1:
- CogVideo: https://github.com/THUDM/CogVideo/
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
- Wan2.1: https://github.com/Wan-Video/Wan2.1/
+- ComfyUI-KJNodes: https://github.com/kijai/ComfyUI-KJNodes
+- ComfyUI-EasyAnimateWrapper: https://github.com/kijai/ComfyUI-EasyAnimateWrapper
+- ComfyUI-CameraCtrl-Wrapper: https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper
+- CameraCtrl: https://github.com/hehao13/CameraCtrl
# 许可证
本项目采用 [Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE).
diff --git a/asset/6.png b/asset/6.png
new file mode 100644
index 0000000..0e40ba9
Binary files /dev/null and b/asset/6.png differ
diff --git a/asset/7.png b/asset/7.png
new file mode 100644
index 0000000..9a107af
Binary files /dev/null and b/asset/7.png differ
diff --git a/asset/Pan_Down.txt b/asset/Pan_Down.txt
new file mode 100644
index 0000000..22fe5d2
--- /dev/null
+++ b/asset/Pan_Down.txt
@@ -0,0 +1,82 @@
+
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.018518518518518517 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.037037037037037035 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.05555555555555555 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.07407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.09259259259259259 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.1111111111111111 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.12962962962962962 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.14814814814814814 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.16666666666666666 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.18518518518518517 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.2037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.2222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.24074074074074073 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.25925925925925924 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.2777777777777778 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.2962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.31481481481481477 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.3333333333333333 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.35185185185185186 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.37037037037037035 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.38888888888888884 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.4074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.42592592592592593 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.4444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.4629629629629629 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.48148148148148145 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5185185185185185 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.537037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5555555555555556 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5740740740740741 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5925925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.611111111111111 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.6296296296296295 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.6481481481481481 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.6666666666666666 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.6851851851851851 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7592592592592593 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7777777777777777 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8148148148148148 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8333333333333334 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8518518518518519 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8703703703703705 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8888888888888888 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9259259259259258 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9629629629629629 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9814814814814815 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.0185185185185186 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.0555555555555556 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.0925925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1111111111111112 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1296296296296298 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1481481481481481 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1666666666666667 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1851851851851851 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.2037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.2407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.259259259259259 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.2777777777777777 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.2962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3148148148148149 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3333333333333333 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3518518518518519 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3703703703703702 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3888888888888888 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.4074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.425925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.4444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.462962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.4814814814814814 0.0 0.0 1.0 0.0
diff --git a/asset/Pan_Left.txt b/asset/Pan_Left.txt
new file mode 100644
index 0000000..3e277a9
--- /dev/null
+++ b/asset/Pan_Left.txt
@@ -0,0 +1,82 @@
+
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.018518518518518517 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.037037037037037035 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.05555555555555555 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.07407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.09259259259259259 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.1111111111111111 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.12962962962962962 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.14814814814814814 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.16666666666666666 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.18518518518518517 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.24074074074074073 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.25925925925925924 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2777777777777778 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.31481481481481477 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.3333333333333333 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.35185185185185186 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.37037037037037035 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.38888888888888884 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.42592592592592593 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4629629629629629 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.48148148148148145 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5185185185185185 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.537037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5555555555555556 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5740740740740741 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5925925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.611111111111111 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6296296296296295 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6481481481481481 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6666666666666666 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6851851851851851 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7592592592592593 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7777777777777777 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8148148148148148 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8333333333333334 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8518518518518519 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8703703703703705 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8888888888888888 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9259259259259258 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9629629629629629 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9814814814814815 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0185185185185186 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0555555555555556 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0925925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1111111111111112 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1296296296296298 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1481481481481481 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1666666666666667 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1851851851851851 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.259259259259259 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2777777777777777 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3148148148148149 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3333333333333333 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3518518518518519 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3703703703703702 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3888888888888888 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.425925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.462962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4814814814814814 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
diff --git a/asset/Pan_Left_Down.txt b/asset/Pan_Left_Down.txt
new file mode 100644
index 0000000..f59a0df
--- /dev/null
+++ b/asset/Pan_Left_Down.txt
@@ -0,0 +1,82 @@
+
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.018518518518518517 0.0 1.0 0.0 -0.018518518518518517 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.037037037037037035 0.0 1.0 0.0 -0.037037037037037035 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.05555555555555555 0.0 1.0 0.0 -0.05555555555555555 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.07407407407407407 0.0 1.0 0.0 -0.07407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.09259259259259259 0.0 1.0 0.0 -0.09259259259259259 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.1111111111111111 0.0 1.0 0.0 -0.1111111111111111 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.12962962962962962 0.0 1.0 0.0 -0.12962962962962962 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.14814814814814814 0.0 1.0 0.0 -0.14814814814814814 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.16666666666666666 0.0 1.0 0.0 -0.16666666666666666 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.18518518518518517 0.0 1.0 0.0 -0.18518518518518517 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2037037037037037 0.0 1.0 0.0 -0.2037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2222222222222222 0.0 1.0 0.0 -0.2222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.24074074074074073 0.0 1.0 0.0 -0.24074074074074073 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.25925925925925924 0.0 1.0 0.0 -0.25925925925925924 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2777777777777778 0.0 1.0 0.0 -0.2777777777777778 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2962962962962963 0.0 1.0 0.0 -0.2962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.31481481481481477 0.0 1.0 0.0 -0.31481481481481477 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.3333333333333333 0.0 1.0 0.0 -0.3333333333333333 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.35185185185185186 0.0 1.0 0.0 -0.35185185185185186 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.37037037037037035 0.0 1.0 0.0 -0.37037037037037035 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.38888888888888884 0.0 1.0 0.0 -0.38888888888888884 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4074074074074074 0.0 1.0 0.0 -0.4074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.42592592592592593 0.0 1.0 0.0 -0.42592592592592593 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4444444444444444 0.0 1.0 0.0 -0.4444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4629629629629629 0.0 1.0 0.0 -0.4629629629629629 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.48148148148148145 0.0 1.0 0.0 -0.48148148148148145 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5 0.0 1.0 0.0 -0.5 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5185185185185185 0.0 1.0 0.0 -0.5185185185185185 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.537037037037037 0.0 1.0 0.0 -0.537037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5555555555555556 0.0 1.0 0.0 -0.5555555555555556 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5740740740740741 0.0 1.0 0.0 -0.5740740740740741 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5925925925925926 0.0 1.0 0.0 -0.5925925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.611111111111111 0.0 1.0 0.0 -0.611111111111111 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6296296296296295 0.0 1.0 0.0 -0.6296296296296295 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6481481481481481 0.0 1.0 0.0 -0.6481481481481481 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6666666666666666 0.0 1.0 0.0 -0.6666666666666666 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6851851851851851 0.0 1.0 0.0 -0.6851851851851851 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7037037037037037 0.0 1.0 0.0 -0.7037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7222222222222222 0.0 1.0 0.0 -0.7222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7407407407407407 0.0 1.0 0.0 -0.7407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7592592592592593 0.0 1.0 0.0 -0.7592592592592593 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7777777777777777 0.0 1.0 0.0 -0.7777777777777777 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7962962962962963 0.0 1.0 0.0 -0.7962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8148148148148148 0.0 1.0 0.0 -0.8148148148148148 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8333333333333334 0.0 1.0 0.0 -0.8333333333333334 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8518518518518519 0.0 1.0 0.0 -0.8518518518518519 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8703703703703705 0.0 1.0 0.0 -0.8703703703703705 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8888888888888888 0.0 1.0 0.0 -0.8888888888888888 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9074074074074074 0.0 1.0 0.0 -0.9074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9259259259259258 0.0 1.0 0.0 -0.9259259259259258 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9444444444444444 0.0 1.0 0.0 -0.9444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9629629629629629 0.0 1.0 0.0 -0.9629629629629629 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9814814814814815 0.0 1.0 0.0 -0.9814814814814815 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0 0.0 1.0 0.0 -1.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0185185185185186 0.0 1.0 0.0 -1.0185185185185186 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.037037037037037 0.0 1.0 0.0 -1.037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0555555555555556 0.0 1.0 0.0 -1.0555555555555556 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.074074074074074 0.0 1.0 0.0 -1.074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0925925925925926 0.0 1.0 0.0 -1.0925925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1111111111111112 0.0 1.0 0.0 -1.1111111111111112 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1296296296296298 0.0 1.0 0.0 -1.1296296296296298 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1481481481481481 0.0 1.0 0.0 -1.1481481481481481 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1666666666666667 0.0 1.0 0.0 -1.1666666666666667 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1851851851851851 0.0 1.0 0.0 -1.1851851851851851 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2037037037037037 0.0 1.0 0.0 -1.2037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.222222222222222 0.0 1.0 0.0 -1.222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2407407407407407 0.0 1.0 0.0 -1.2407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.259259259259259 0.0 1.0 0.0 -1.259259259259259 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2777777777777777 0.0 1.0 0.0 -1.2777777777777777 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2962962962962963 0.0 1.0 0.0 -1.2962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3148148148148149 0.0 1.0 0.0 -1.3148148148148149 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3333333333333333 0.0 1.0 0.0 -1.3333333333333333 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3518518518518519 0.0 1.0 0.0 -1.3518518518518519 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3703703703703702 0.0 1.0 0.0 -1.3703703703703702 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3888888888888888 0.0 1.0 0.0 -1.3888888888888888 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4074074074074074 0.0 1.0 0.0 -1.4074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.425925925925926 0.0 1.0 0.0 -1.425925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4444444444444444 0.0 1.0 0.0 -1.4444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.462962962962963 0.0 1.0 0.0 -1.462962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4814814814814814 0.0 1.0 0.0 -1.4814814814814814 0.0 0.0 1.0 0.0
diff --git a/asset/Pan_Left_Up.txt b/asset/Pan_Left_Up.txt
new file mode 100644
index 0000000..0dd1580
--- /dev/null
+++ b/asset/Pan_Left_Up.txt
@@ -0,0 +1,82 @@
+
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.018518518518518517 0.0 1.0 0.0 0.018518518518518517 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.037037037037037035 0.0 1.0 0.0 0.037037037037037035 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.05555555555555555 0.0 1.0 0.0 0.05555555555555555 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.07407407407407407 0.0 1.0 0.0 0.07407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.09259259259259259 0.0 1.0 0.0 0.09259259259259259 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.1111111111111111 0.0 1.0 0.0 0.1111111111111111 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.12962962962962962 0.0 1.0 0.0 0.12962962962962962 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.14814814814814814 0.0 1.0 0.0 0.14814814814814814 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.16666666666666666 0.0 1.0 0.0 0.16666666666666666 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.18518518518518517 0.0 1.0 0.0 0.18518518518518517 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2037037037037037 0.0 1.0 0.0 0.2037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2222222222222222 0.0 1.0 0.0 0.2222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.24074074074074073 0.0 1.0 0.0 0.24074074074074073 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.25925925925925924 0.0 1.0 0.0 0.25925925925925924 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2777777777777778 0.0 1.0 0.0 0.2777777777777778 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2962962962962963 0.0 1.0 0.0 0.2962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.31481481481481477 0.0 1.0 0.0 0.31481481481481477 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.3333333333333333 0.0 1.0 0.0 0.3333333333333333 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.35185185185185186 0.0 1.0 0.0 0.35185185185185186 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.37037037037037035 0.0 1.0 0.0 0.37037037037037035 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.38888888888888884 0.0 1.0 0.0 0.38888888888888884 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4074074074074074 0.0 1.0 0.0 0.4074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.42592592592592593 0.0 1.0 0.0 0.42592592592592593 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4444444444444444 0.0 1.0 0.0 0.4444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4629629629629629 0.0 1.0 0.0 0.4629629629629629 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.48148148148148145 0.0 1.0 0.0 0.48148148148148145 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5 0.0 1.0 0.0 0.5 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5185185185185185 0.0 1.0 0.0 0.5185185185185185 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.537037037037037 0.0 1.0 0.0 0.537037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5555555555555556 0.0 1.0 0.0 0.5555555555555556 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5740740740740741 0.0 1.0 0.0 0.5740740740740741 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5925925925925926 0.0 1.0 0.0 0.5925925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.611111111111111 0.0 1.0 0.0 0.611111111111111 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6296296296296295 0.0 1.0 0.0 0.6296296296296295 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6481481481481481 0.0 1.0 0.0 0.6481481481481481 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6666666666666666 0.0 1.0 0.0 0.6666666666666666 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6851851851851851 0.0 1.0 0.0 0.6851851851851851 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7037037037037037 0.0 1.0 0.0 0.7037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7222222222222222 0.0 1.0 0.0 0.7222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7407407407407407 0.0 1.0 0.0 0.7407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7592592592592593 0.0 1.0 0.0 0.7592592592592593 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7777777777777777 0.0 1.0 0.0 0.7777777777777777 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7962962962962963 0.0 1.0 0.0 0.7962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8148148148148148 0.0 1.0 0.0 0.8148148148148148 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8333333333333334 0.0 1.0 0.0 0.8333333333333334 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8518518518518519 0.0 1.0 0.0 0.8518518518518519 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8703703703703705 0.0 1.0 0.0 0.8703703703703705 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8888888888888888 0.0 1.0 0.0 0.8888888888888888 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9074074074074074 0.0 1.0 0.0 0.9074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9259259259259258 0.0 1.0 0.0 0.9259259259259258 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9444444444444444 0.0 1.0 0.0 0.9444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9629629629629629 0.0 1.0 0.0 0.9629629629629629 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9814814814814815 0.0 1.0 0.0 0.9814814814814815 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0 0.0 1.0 0.0 1.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0185185185185186 0.0 1.0 0.0 1.0185185185185186 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.037037037037037 0.0 1.0 0.0 1.037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0555555555555556 0.0 1.0 0.0 1.0555555555555556 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.074074074074074 0.0 1.0 0.0 1.074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0925925925925926 0.0 1.0 0.0 1.0925925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1111111111111112 0.0 1.0 0.0 1.1111111111111112 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1296296296296298 0.0 1.0 0.0 1.1296296296296298 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1481481481481481 0.0 1.0 0.0 1.1481481481481481 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1666666666666667 0.0 1.0 0.0 1.1666666666666667 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1851851851851851 0.0 1.0 0.0 1.1851851851851851 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2037037037037037 0.0 1.0 0.0 1.2037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.222222222222222 0.0 1.0 0.0 1.222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2407407407407407 0.0 1.0 0.0 1.2407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.259259259259259 0.0 1.0 0.0 1.259259259259259 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2777777777777777 0.0 1.0 0.0 1.2777777777777777 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2962962962962963 0.0 1.0 0.0 1.2962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3148148148148149 0.0 1.0 0.0 1.3148148148148149 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3333333333333333 0.0 1.0 0.0 1.3333333333333333 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3518518518518519 0.0 1.0 0.0 1.3518518518518519 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3703703703703702 0.0 1.0 0.0 1.3703703703703702 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3888888888888888 0.0 1.0 0.0 1.3888888888888888 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4074074074074074 0.0 1.0 0.0 1.4074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.425925925925926 0.0 1.0 0.0 1.425925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4444444444444444 0.0 1.0 0.0 1.4444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.462962962962963 0.0 1.0 0.0 1.462962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4814814814814814 0.0 1.0 0.0 1.4814814814814814 0.0 0.0 1.0 0.0
diff --git a/asset/Pan_Right.txt b/asset/Pan_Right.txt
new file mode 100644
index 0000000..0f5383e
--- /dev/null
+++ b/asset/Pan_Right.txt
@@ -0,0 +1,82 @@
+
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.018518518518518517 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.037037037037037035 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.05555555555555555 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.07407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.09259259259259259 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.1111111111111111 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.12962962962962962 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.14814814814814814 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.16666666666666666 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.18518518518518517 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.24074074074074073 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.25925925925925924 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2777777777777778 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.31481481481481477 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.3333333333333333 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.35185185185185186 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.37037037037037035 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.38888888888888884 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.42592592592592593 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4629629629629629 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.48148148148148145 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5185185185185185 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.537037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5555555555555556 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5740740740740741 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5925925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.611111111111111 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6296296296296295 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6481481481481481 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6666666666666666 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6851851851851851 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7592592592592593 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7777777777777777 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8148148148148148 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8333333333333334 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8518518518518519 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8703703703703705 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8888888888888888 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9259259259259258 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9629629629629629 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9814814814814815 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0185185185185186 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0555555555555556 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0925925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1111111111111112 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1296296296296298 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1481481481481481 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1666666666666667 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1851851851851851 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.259259259259259 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2777777777777777 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3148148148148149 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3333333333333333 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3518518518518519 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3703703703703702 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3888888888888888 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.425925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.462962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4814814814814814 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
diff --git a/asset/Pan_Right_Down.txt b/asset/Pan_Right_Down.txt
new file mode 100644
index 0000000..04b64e9
--- /dev/null
+++ b/asset/Pan_Right_Down.txt
@@ -0,0 +1,82 @@
+
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.0 0.0 1.0 0.0 -0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.018518518518518517 0.0 1.0 0.0 -0.018518518518518517 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.037037037037037035 0.0 1.0 0.0 -0.037037037037037035 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.05555555555555555 0.0 1.0 0.0 -0.05555555555555555 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.07407407407407407 0.0 1.0 0.0 -0.07407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.09259259259259259 0.0 1.0 0.0 -0.09259259259259259 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.1111111111111111 0.0 1.0 0.0 -0.1111111111111111 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.12962962962962962 0.0 1.0 0.0 -0.12962962962962962 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.14814814814814814 0.0 1.0 0.0 -0.14814814814814814 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.16666666666666666 0.0 1.0 0.0 -0.16666666666666666 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.18518518518518517 0.0 1.0 0.0 -0.18518518518518517 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2037037037037037 0.0 1.0 0.0 -0.2037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2222222222222222 0.0 1.0 0.0 -0.2222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.24074074074074073 0.0 1.0 0.0 -0.24074074074074073 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.25925925925925924 0.0 1.0 0.0 -0.25925925925925924 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2777777777777778 0.0 1.0 0.0 -0.2777777777777778 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2962962962962963 0.0 1.0 0.0 -0.2962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.31481481481481477 0.0 1.0 0.0 -0.31481481481481477 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.3333333333333333 0.0 1.0 0.0 -0.3333333333333333 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.35185185185185186 0.0 1.0 0.0 -0.35185185185185186 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.37037037037037035 0.0 1.0 0.0 -0.37037037037037035 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.38888888888888884 0.0 1.0 0.0 -0.38888888888888884 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4074074074074074 0.0 1.0 0.0 -0.4074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.42592592592592593 0.0 1.0 0.0 -0.42592592592592593 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4444444444444444 0.0 1.0 0.0 -0.4444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4629629629629629 0.0 1.0 0.0 -0.4629629629629629 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.48148148148148145 0.0 1.0 0.0 -0.48148148148148145 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5 0.0 1.0 0.0 -0.5 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5185185185185185 0.0 1.0 0.0 -0.5185185185185185 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.537037037037037 0.0 1.0 0.0 -0.537037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5555555555555556 0.0 1.0 0.0 -0.5555555555555556 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5740740740740741 0.0 1.0 0.0 -0.5740740740740741 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5925925925925926 0.0 1.0 0.0 -0.5925925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.611111111111111 0.0 1.0 0.0 -0.611111111111111 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6296296296296295 0.0 1.0 0.0 -0.6296296296296295 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6481481481481481 0.0 1.0 0.0 -0.6481481481481481 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6666666666666666 0.0 1.0 0.0 -0.6666666666666666 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6851851851851851 0.0 1.0 0.0 -0.6851851851851851 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7037037037037037 0.0 1.0 0.0 -0.7037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7222222222222222 0.0 1.0 0.0 -0.7222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7407407407407407 0.0 1.0 0.0 -0.7407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7592592592592593 0.0 1.0 0.0 -0.7592592592592593 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7777777777777777 0.0 1.0 0.0 -0.7777777777777777 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7962962962962963 0.0 1.0 0.0 -0.7962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8148148148148148 0.0 1.0 0.0 -0.8148148148148148 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8333333333333334 0.0 1.0 0.0 -0.8333333333333334 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8518518518518519 0.0 1.0 0.0 -0.8518518518518519 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8703703703703705 0.0 1.0 0.0 -0.8703703703703705 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8888888888888888 0.0 1.0 0.0 -0.8888888888888888 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9074074074074074 0.0 1.0 0.0 -0.9074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9259259259259258 0.0 1.0 0.0 -0.9259259259259258 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9444444444444444 0.0 1.0 0.0 -0.9444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9629629629629629 0.0 1.0 0.0 -0.9629629629629629 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9814814814814815 0.0 1.0 0.0 -0.9814814814814815 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0 0.0 1.0 0.0 -1.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0185185185185186 0.0 1.0 0.0 -1.0185185185185186 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.037037037037037 0.0 1.0 0.0 -1.037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0555555555555556 0.0 1.0 0.0 -1.0555555555555556 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.074074074074074 0.0 1.0 0.0 -1.074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0925925925925926 0.0 1.0 0.0 -1.0925925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1111111111111112 0.0 1.0 0.0 -1.1111111111111112 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1296296296296298 0.0 1.0 0.0 -1.1296296296296298 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1481481481481481 0.0 1.0 0.0 -1.1481481481481481 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1666666666666667 0.0 1.0 0.0 -1.1666666666666667 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1851851851851851 0.0 1.0 0.0 -1.1851851851851851 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2037037037037037 0.0 1.0 0.0 -1.2037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.222222222222222 0.0 1.0 0.0 -1.222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2407407407407407 0.0 1.0 0.0 -1.2407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.259259259259259 0.0 1.0 0.0 -1.259259259259259 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2777777777777777 0.0 1.0 0.0 -1.2777777777777777 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2962962962962963 0.0 1.0 0.0 -1.2962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3148148148148149 0.0 1.0 0.0 -1.3148148148148149 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3333333333333333 0.0 1.0 0.0 -1.3333333333333333 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3518518518518519 0.0 1.0 0.0 -1.3518518518518519 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3703703703703702 0.0 1.0 0.0 -1.3703703703703702 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3888888888888888 0.0 1.0 0.0 -1.3888888888888888 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4074074074074074 0.0 1.0 0.0 -1.4074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.425925925925926 0.0 1.0 0.0 -1.425925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4444444444444444 0.0 1.0 0.0 -1.4444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.462962962962963 0.0 1.0 0.0 -1.462962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4814814814814814 0.0 1.0 0.0 -1.4814814814814814 0.0 0.0 1.0 0.0
diff --git a/asset/Pan_Right_Up.txt b/asset/Pan_Right_Up.txt
new file mode 100644
index 0000000..3271a44
--- /dev/null
+++ b/asset/Pan_Right_Up.txt
@@ -0,0 +1,82 @@
+
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.018518518518518517 0.0 1.0 0.0 0.018518518518518517 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.037037037037037035 0.0 1.0 0.0 0.037037037037037035 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.05555555555555555 0.0 1.0 0.0 0.05555555555555555 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.07407407407407407 0.0 1.0 0.0 0.07407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.09259259259259259 0.0 1.0 0.0 0.09259259259259259 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.1111111111111111 0.0 1.0 0.0 0.1111111111111111 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.12962962962962962 0.0 1.0 0.0 0.12962962962962962 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.14814814814814814 0.0 1.0 0.0 0.14814814814814814 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.16666666666666666 0.0 1.0 0.0 0.16666666666666666 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.18518518518518517 0.0 1.0 0.0 0.18518518518518517 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2037037037037037 0.0 1.0 0.0 0.2037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2222222222222222 0.0 1.0 0.0 0.2222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.24074074074074073 0.0 1.0 0.0 0.24074074074074073 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.25925925925925924 0.0 1.0 0.0 0.25925925925925924 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2777777777777778 0.0 1.0 0.0 0.2777777777777778 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2962962962962963 0.0 1.0 0.0 0.2962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.31481481481481477 0.0 1.0 0.0 0.31481481481481477 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.3333333333333333 0.0 1.0 0.0 0.3333333333333333 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.35185185185185186 0.0 1.0 0.0 0.35185185185185186 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.37037037037037035 0.0 1.0 0.0 0.37037037037037035 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.38888888888888884 0.0 1.0 0.0 0.38888888888888884 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4074074074074074 0.0 1.0 0.0 0.4074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.42592592592592593 0.0 1.0 0.0 0.42592592592592593 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4444444444444444 0.0 1.0 0.0 0.4444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4629629629629629 0.0 1.0 0.0 0.4629629629629629 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.48148148148148145 0.0 1.0 0.0 0.48148148148148145 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5 0.0 1.0 0.0 0.5 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5185185185185185 0.0 1.0 0.0 0.5185185185185185 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.537037037037037 0.0 1.0 0.0 0.537037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5555555555555556 0.0 1.0 0.0 0.5555555555555556 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5740740740740741 0.0 1.0 0.0 0.5740740740740741 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5925925925925926 0.0 1.0 0.0 0.5925925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.611111111111111 0.0 1.0 0.0 0.611111111111111 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6296296296296295 0.0 1.0 0.0 0.6296296296296295 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6481481481481481 0.0 1.0 0.0 0.6481481481481481 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6666666666666666 0.0 1.0 0.0 0.6666666666666666 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6851851851851851 0.0 1.0 0.0 0.6851851851851851 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7037037037037037 0.0 1.0 0.0 0.7037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7222222222222222 0.0 1.0 0.0 0.7222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7407407407407407 0.0 1.0 0.0 0.7407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7592592592592593 0.0 1.0 0.0 0.7592592592592593 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7777777777777777 0.0 1.0 0.0 0.7777777777777777 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7962962962962963 0.0 1.0 0.0 0.7962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8148148148148148 0.0 1.0 0.0 0.8148148148148148 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8333333333333334 0.0 1.0 0.0 0.8333333333333334 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8518518518518519 0.0 1.0 0.0 0.8518518518518519 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8703703703703705 0.0 1.0 0.0 0.8703703703703705 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8888888888888888 0.0 1.0 0.0 0.8888888888888888 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9074074074074074 0.0 1.0 0.0 0.9074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9259259259259258 0.0 1.0 0.0 0.9259259259259258 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9444444444444444 0.0 1.0 0.0 0.9444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9629629629629629 0.0 1.0 0.0 0.9629629629629629 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9814814814814815 0.0 1.0 0.0 0.9814814814814815 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0 0.0 1.0 0.0 1.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0185185185185186 0.0 1.0 0.0 1.0185185185185186 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.037037037037037 0.0 1.0 0.0 1.037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0555555555555556 0.0 1.0 0.0 1.0555555555555556 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.074074074074074 0.0 1.0 0.0 1.074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0925925925925926 0.0 1.0 0.0 1.0925925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1111111111111112 0.0 1.0 0.0 1.1111111111111112 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1296296296296298 0.0 1.0 0.0 1.1296296296296298 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1481481481481481 0.0 1.0 0.0 1.1481481481481481 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1666666666666667 0.0 1.0 0.0 1.1666666666666667 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1851851851851851 0.0 1.0 0.0 1.1851851851851851 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2037037037037037 0.0 1.0 0.0 1.2037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.222222222222222 0.0 1.0 0.0 1.222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2407407407407407 0.0 1.0 0.0 1.2407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.259259259259259 0.0 1.0 0.0 1.259259259259259 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2777777777777777 0.0 1.0 0.0 1.2777777777777777 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2962962962962963 0.0 1.0 0.0 1.2962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3148148148148149 0.0 1.0 0.0 1.3148148148148149 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3333333333333333 0.0 1.0 0.0 1.3333333333333333 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3518518518518519 0.0 1.0 0.0 1.3518518518518519 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3703703703703702 0.0 1.0 0.0 1.3703703703703702 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3888888888888888 0.0 1.0 0.0 1.3888888888888888 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4074074074074074 0.0 1.0 0.0 1.4074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.425925925925926 0.0 1.0 0.0 1.425925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4444444444444444 0.0 1.0 0.0 1.4444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.462962962962963 0.0 1.0 0.0 1.462962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4814814814814814 0.0 1.0 0.0 1.4814814814814814 0.0 0.0 1.0 0.0
diff --git a/asset/Pan_Up.txt b/asset/Pan_Up.txt
new file mode 100644
index 0000000..3962310
--- /dev/null
+++ b/asset/Pan_Up.txt
@@ -0,0 +1,82 @@
+
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.018518518518518517 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.037037037037037035 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.05555555555555555 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.07407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.09259259259259259 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.1111111111111111 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.12962962962962962 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.14814814814814814 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.16666666666666666 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.18518518518518517 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.2037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.2222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.24074074074074073 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.25925925925925924 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.2777777777777778 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.2962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.31481481481481477 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.3333333333333333 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.35185185185185186 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.37037037037037035 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.38888888888888884 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.4074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.42592592592592593 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.4444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.4629629629629629 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.48148148148148145 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5185185185185185 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.537037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5555555555555556 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5740740740740741 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5925925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.611111111111111 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.6296296296296295 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.6481481481481481 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.6666666666666666 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.6851851851851851 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7592592592592593 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7777777777777777 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8148148148148148 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8333333333333334 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8518518518518519 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8703703703703705 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8888888888888888 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9259259259259258 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9629629629629629 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9814814814814815 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.0 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.0185185185185186 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.0555555555555556 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.0925925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1111111111111112 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1296296296296298 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1481481481481481 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1666666666666667 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1851851851851851 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.2037037037037037 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.222222222222222 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.2407407407407407 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.259259259259259 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.2777777777777777 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.2962962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3148148148148149 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3333333333333333 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3518518518518519 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3703703703703702 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3888888888888888 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.4074074074074074 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.425925925925926 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.4444444444444444 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.462962962962963 0.0 0.0 1.0 0.0
+0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.4814814814814814 0.0 0.0 1.0 0.0
diff --git a/asset/pose.mp4 b/asset/pose.mp4
new file mode 100644
index 0000000..1589729
Binary files /dev/null and b/asset/pose.mp4 differ
diff --git a/comfyui/README.md b/comfyui/README.md
old mode 100644
new mode 100755
index 12c689f..ff7a3ce
--- a/comfyui/README.md
+++ b/comfyui/README.md
@@ -9,7 +9,7 @@ Easily use VideoX-Fun and Wan2.1-Fun inside ComfyUI!
### 1. ComfyUI Installation
#### Option 1: Install via ComfyUI Manager
-TBD
+
#### Option 2: Install manually
The VideoX-Fun repository needs to be placed at `ComfyUI/custom_nodes/VideoX-Fun/`.
@@ -39,6 +39,16 @@ remote_zoe= "https://huggingface.co/lllyasviel/Annotators/resolve/main/ZoeD_M12_
```
#### i. Wan2.1-Fun
+V1.1:
+| Name | Storage Size | Hugging Face | Model Scope | Description |
+|------|--------------|--------------|-------------|-------------|
+| Wan2.1-Fun-V1.1-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP) | Wan2.1-Fun-V1.1-1.3B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
+| Wan2.1-Fun-V1.1-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP) | Wan2.1-Fun-V1.1-14B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
+| Wan2.1-Fun-V1.1-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control) | Wan2.1-Fun-V1.1-1.3B video control weights support various control conditions such as Canny, Depth, Pose, MLSD, etc., supports reference image + control condition-based control, and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
+| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control) | Wan2.1-Fun-V1.1-14B video control weights support various control conditions such as Canny, Depth, Pose, MLSD, etc., supports reference image + control condition-based control, and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
+| Wan2.1-Fun-V1.1-1.3B-Control-Camera | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control) | Wan2.1-Fun-V1.1-1.3B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
+| Wan2.1-Fun-V1.1-14B-Control-Camera | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control) | Wan2.1-Fun-V1.1-14B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
+
V1.0:
| Name | Storage Space | Hugging Face | Model Scope | Description |
|--|--|--|--|--|
@@ -125,39 +135,61 @@ If you want to use lora in CogVideoX-Fun, please put the lora to `ComfyUI/models
## Example workflows
### 1. Wan-Fun
#### i. Image to video generation
-[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.0/wan2.1_fun_workflow_i2v.json) for wan-fun.
+[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_i2v.json) for wan-fun.
Our ui is shown as follow:
-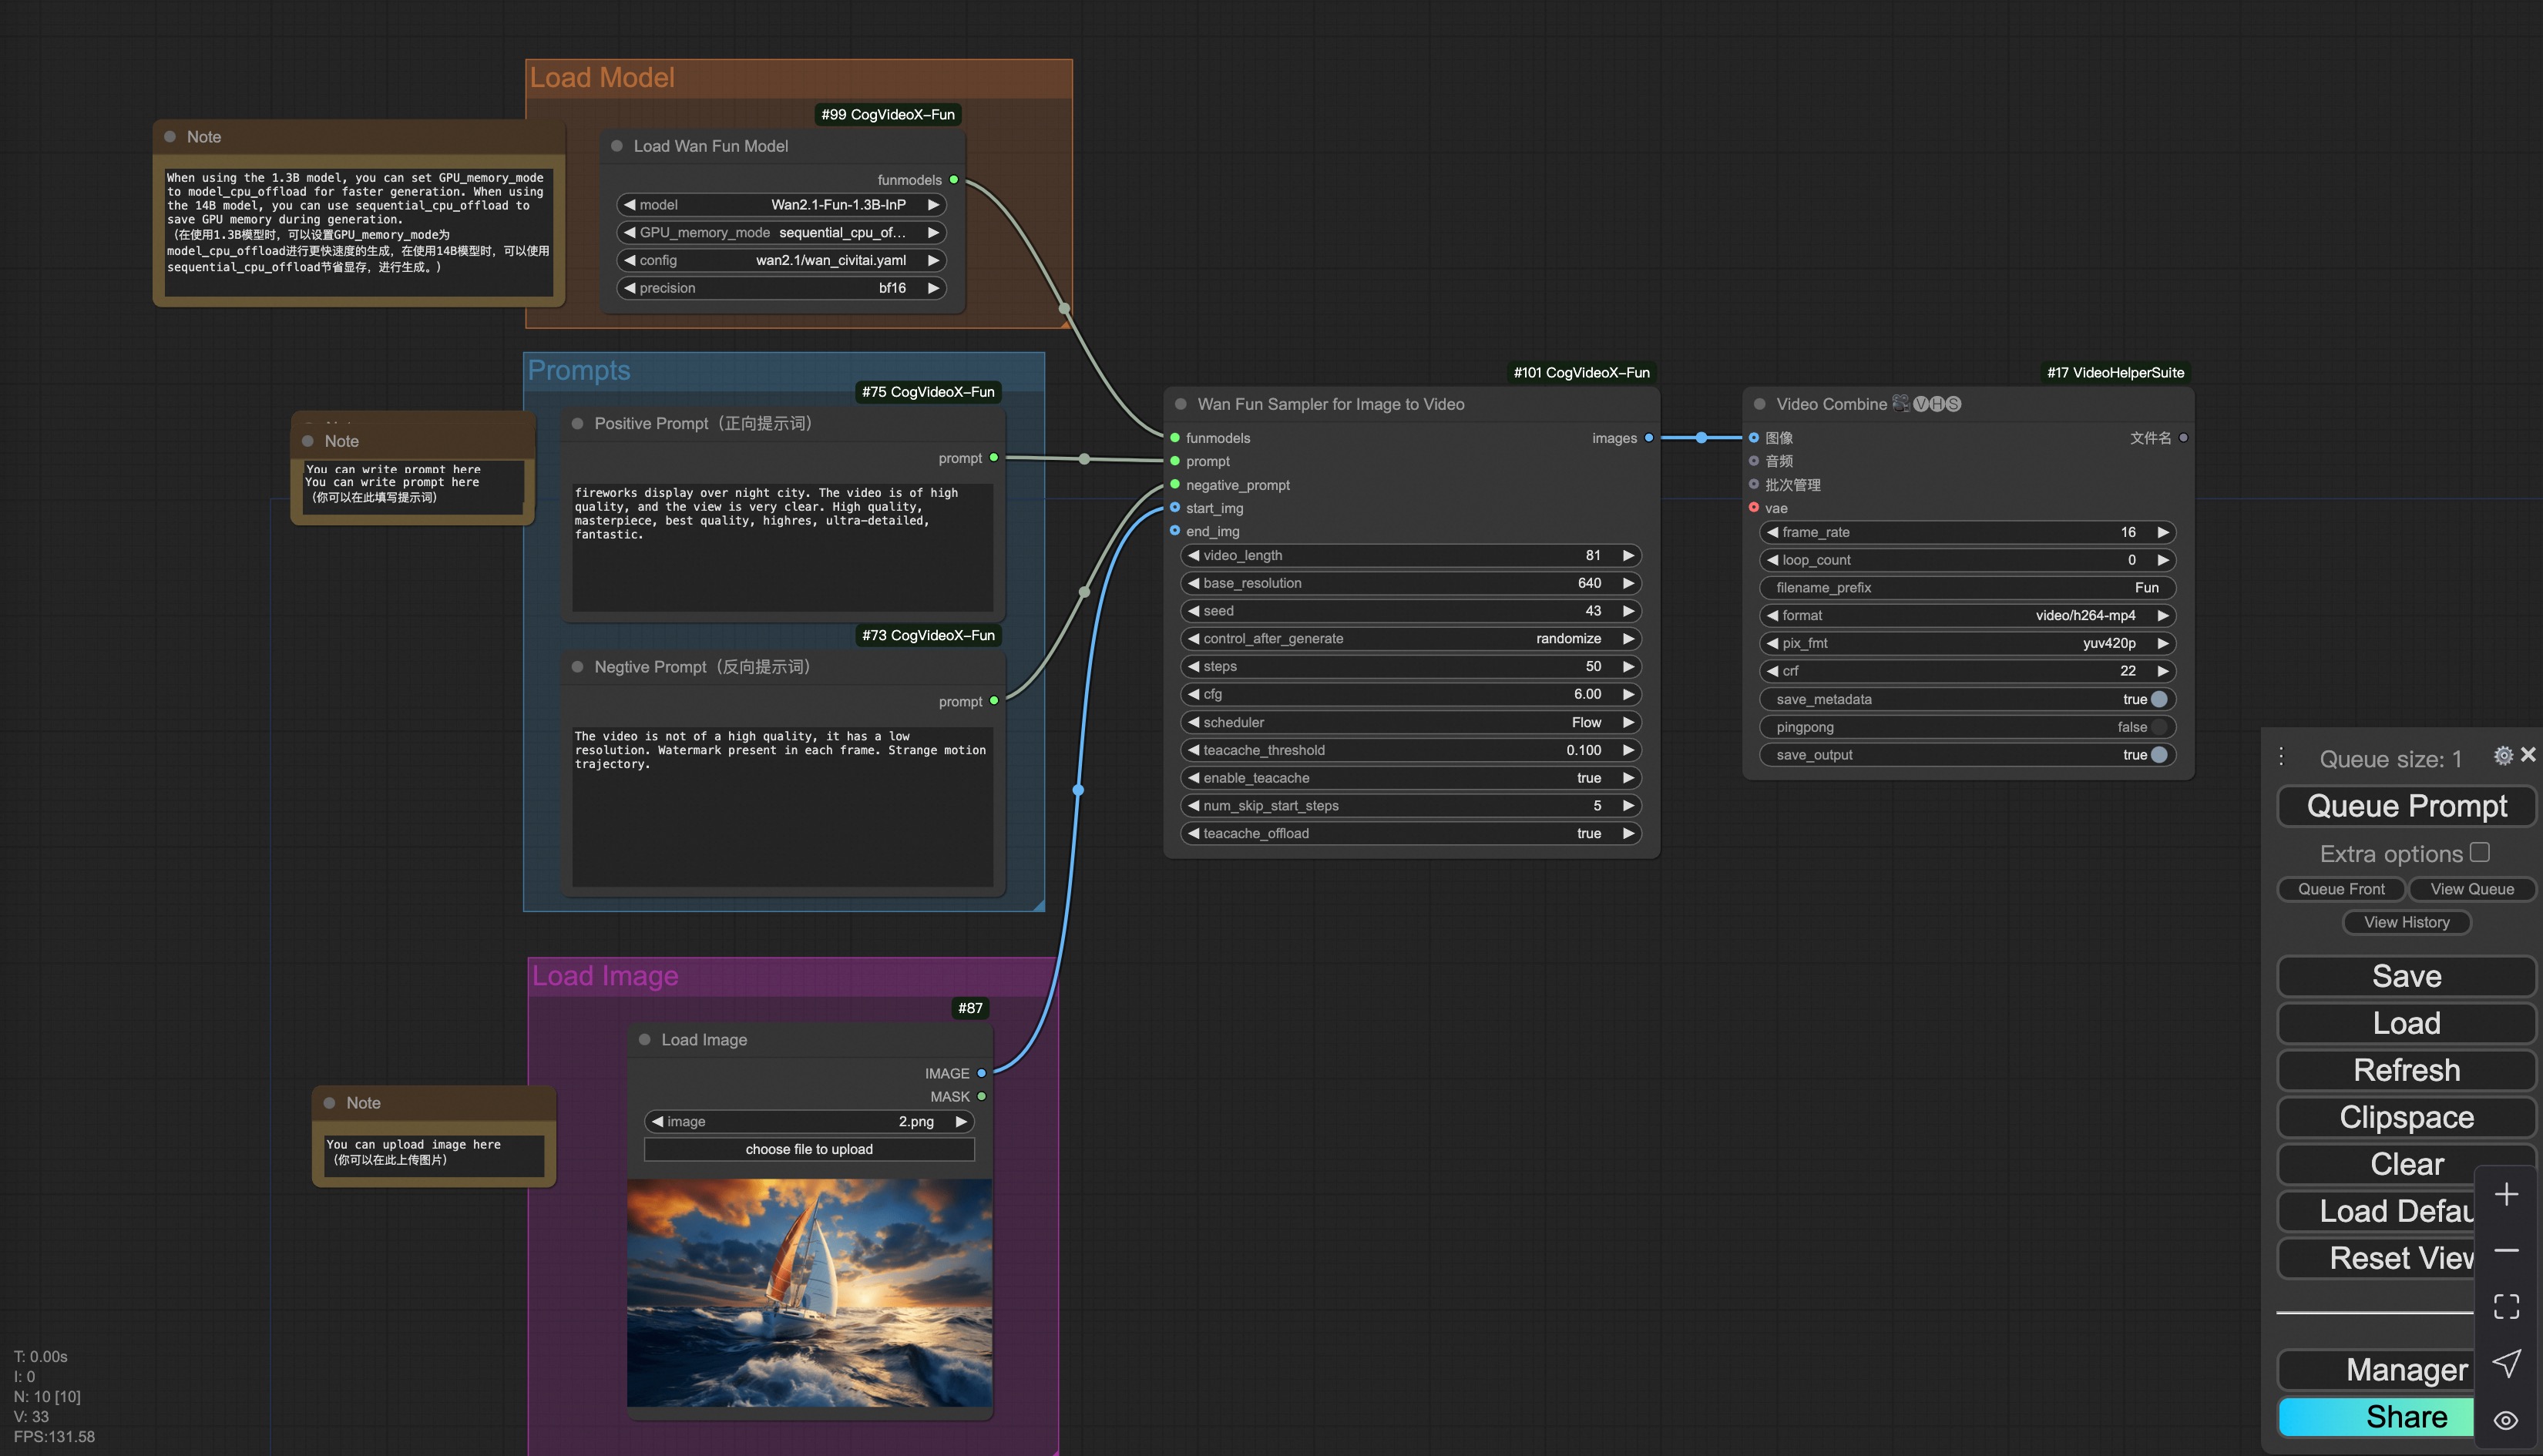
+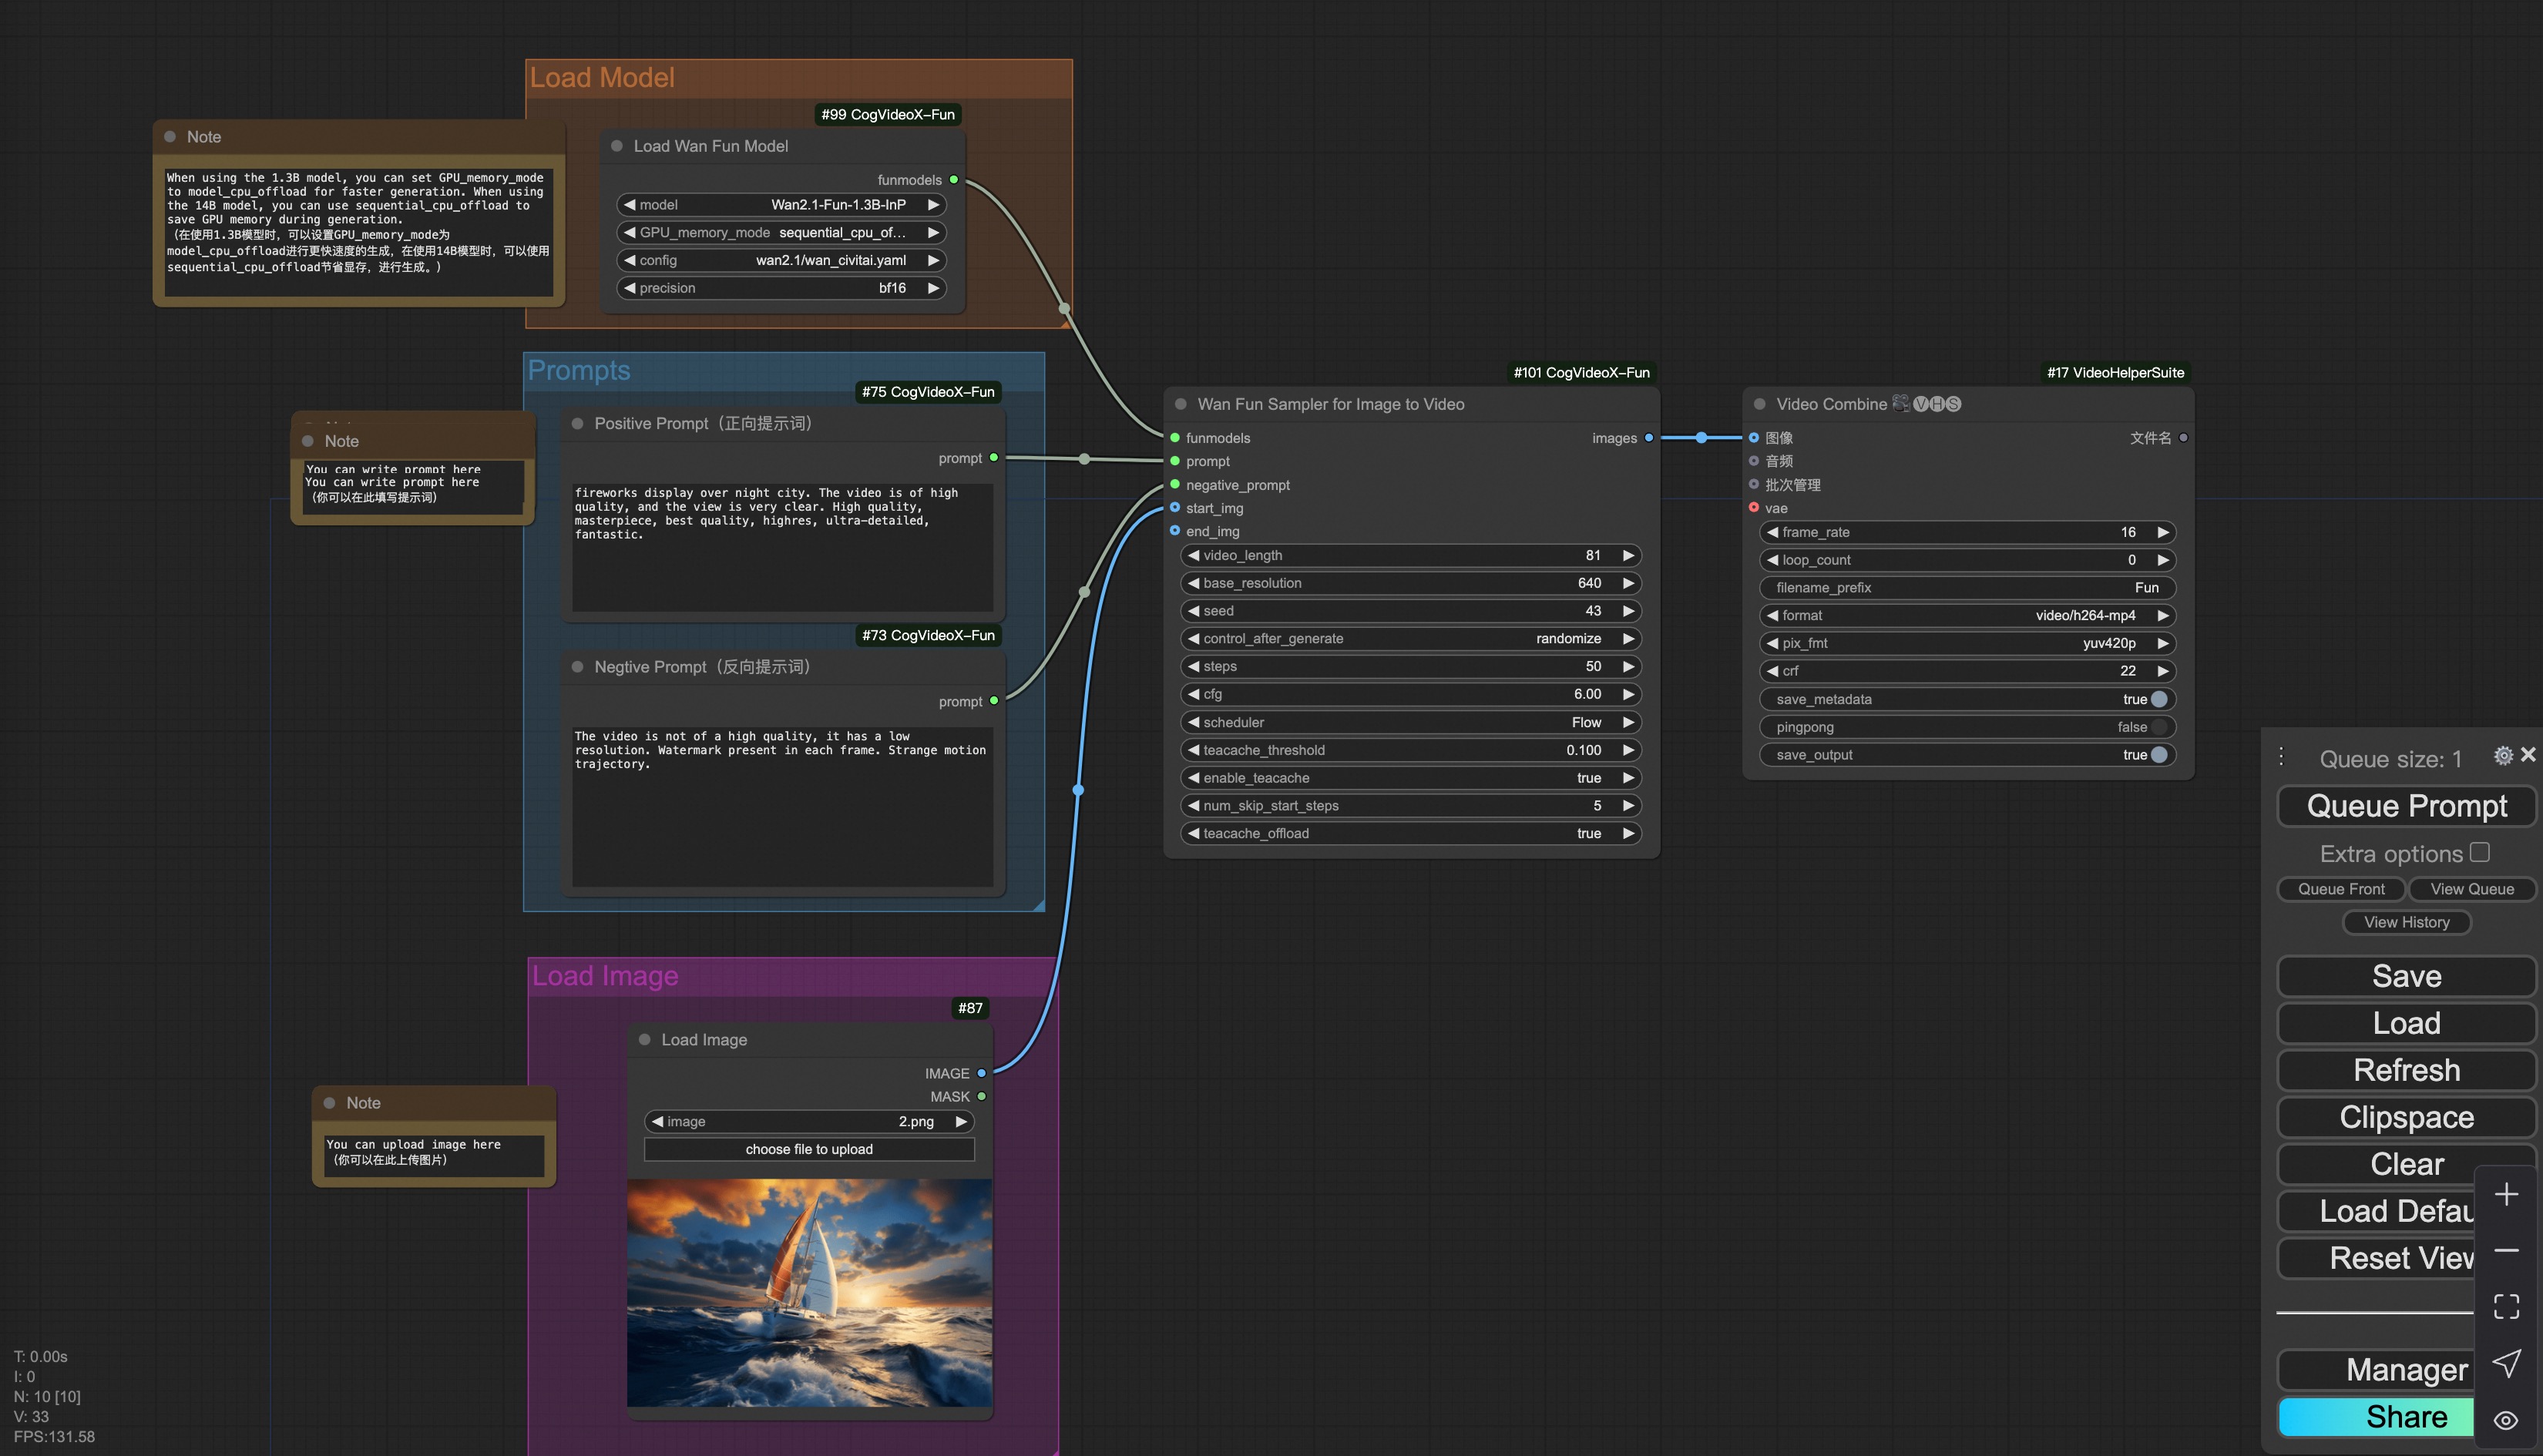
You can run the demo using following photo:

#### ii. Text to video generation
-[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.0/wan2.1_fun_workflow_t2v.json) for wan-fun.
+[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_t2v.json) for wan-fun.
-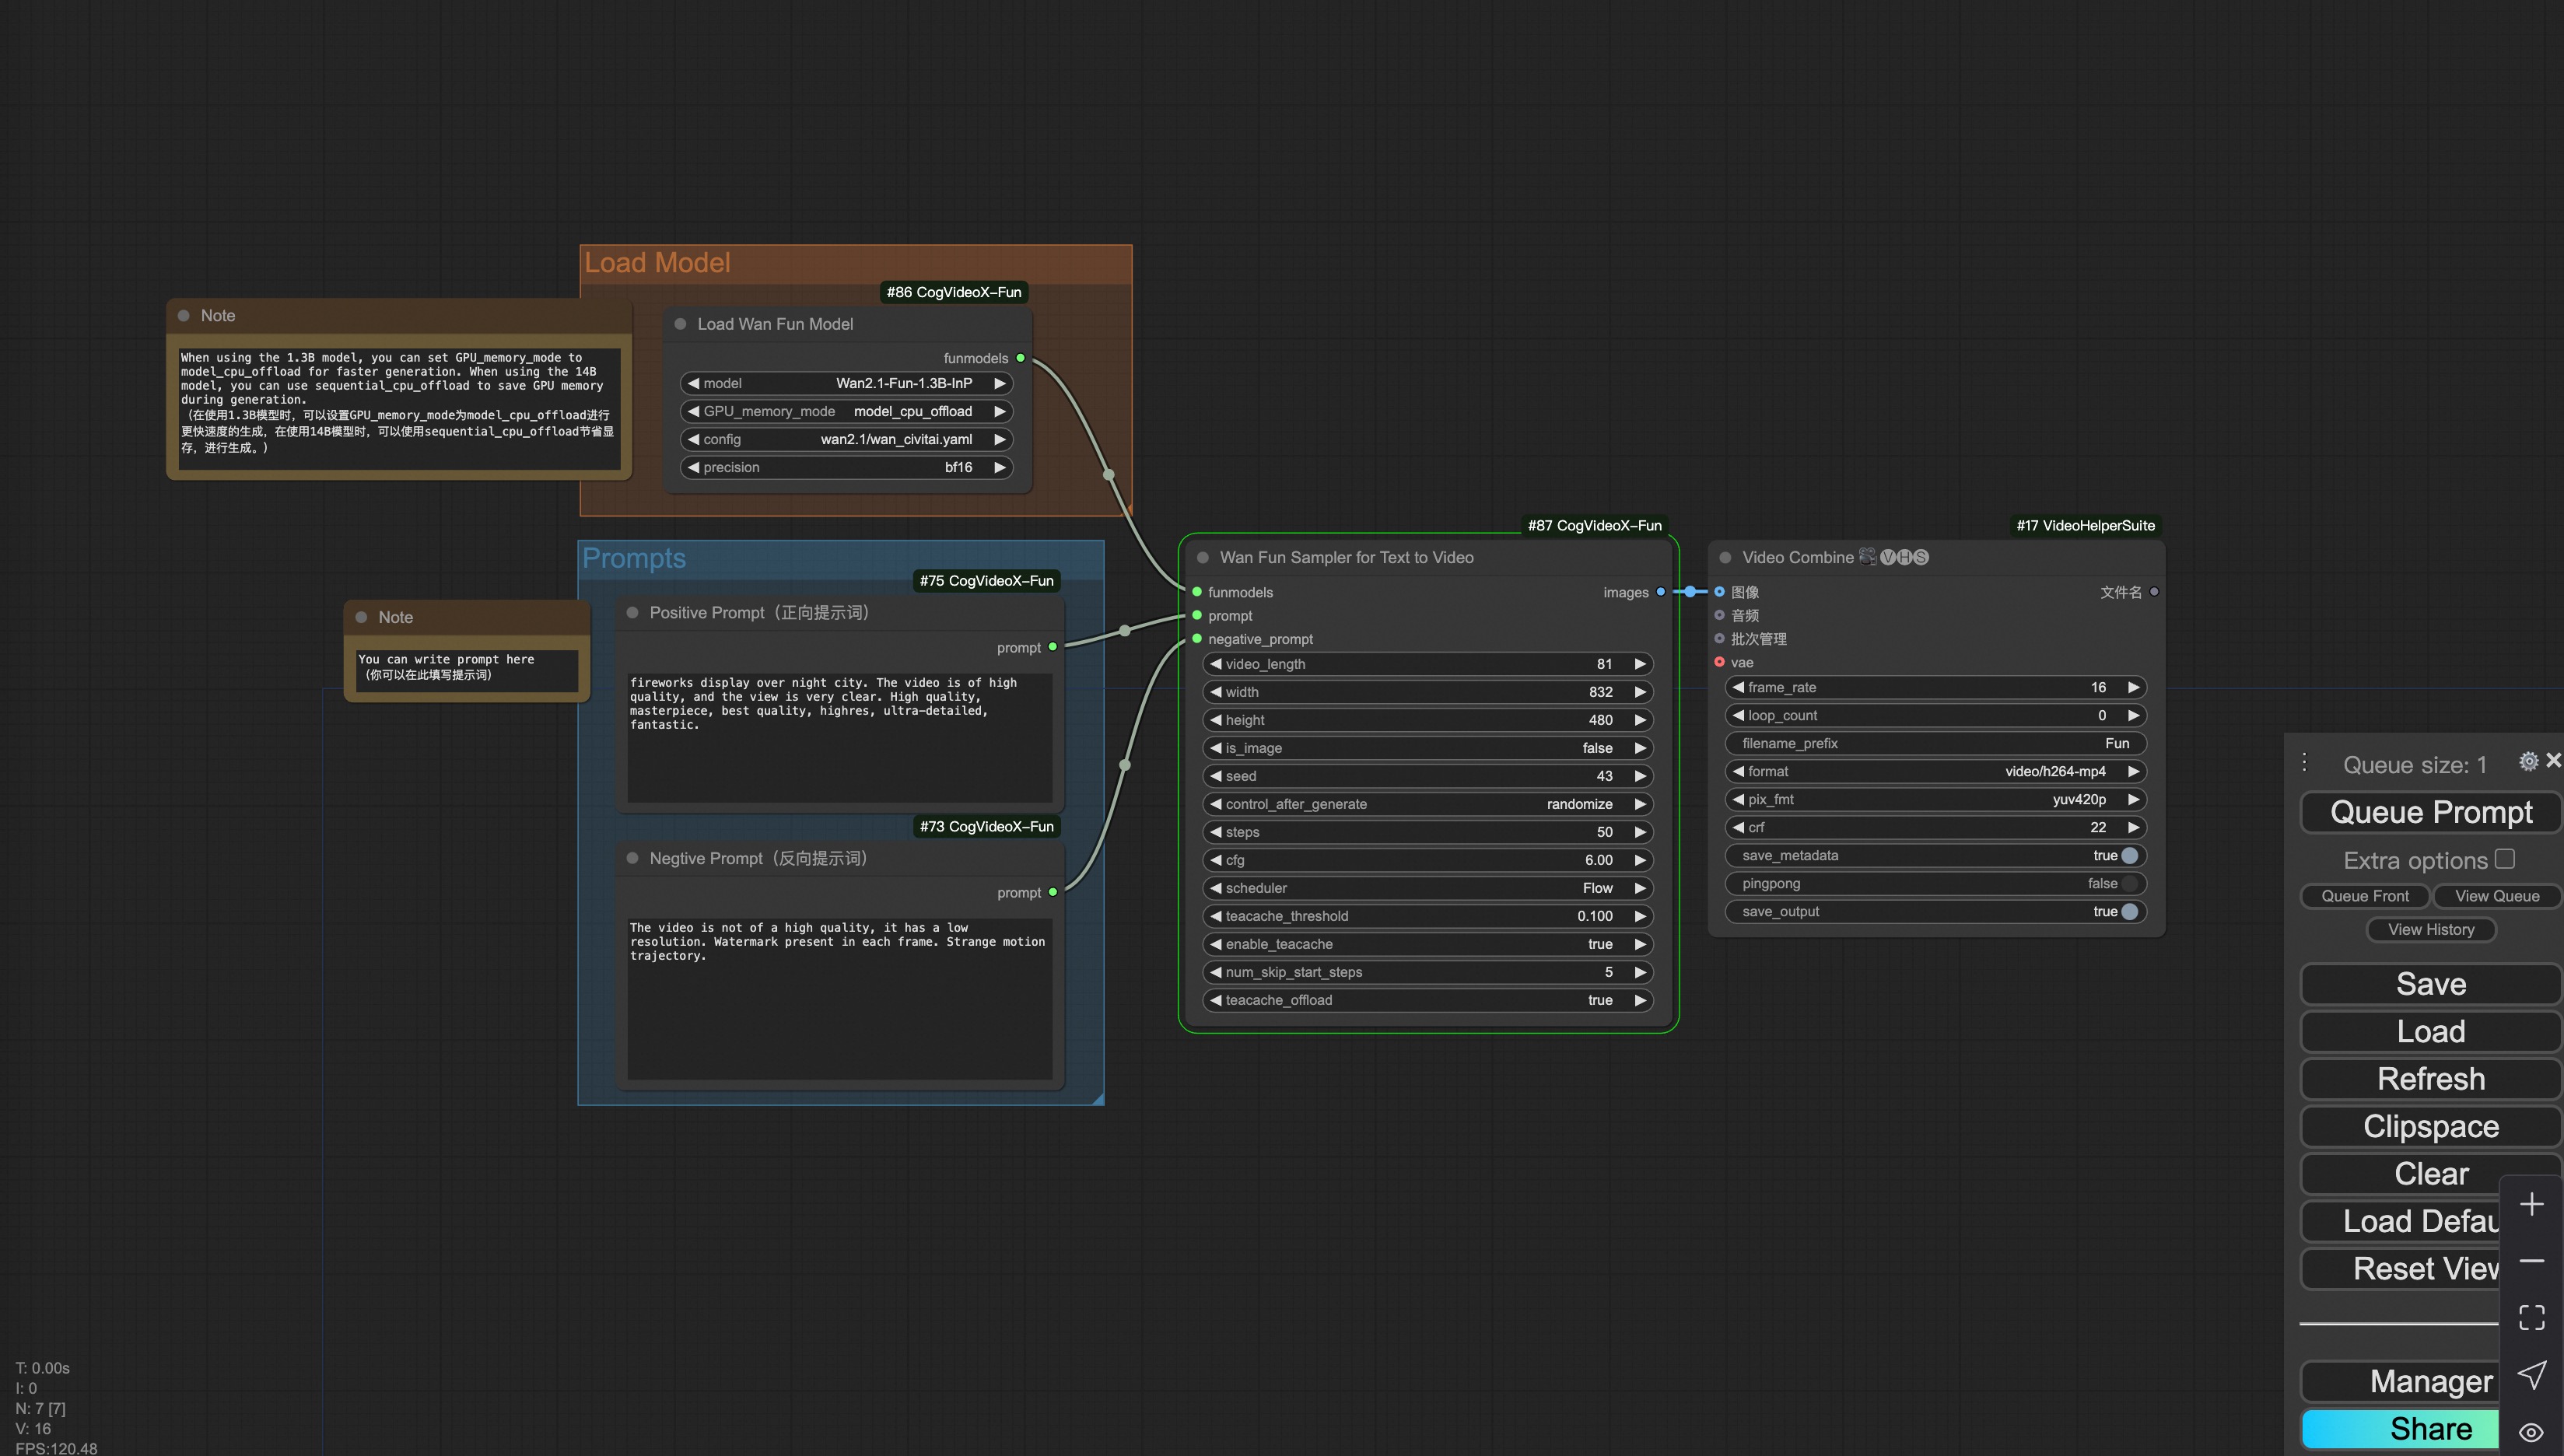
+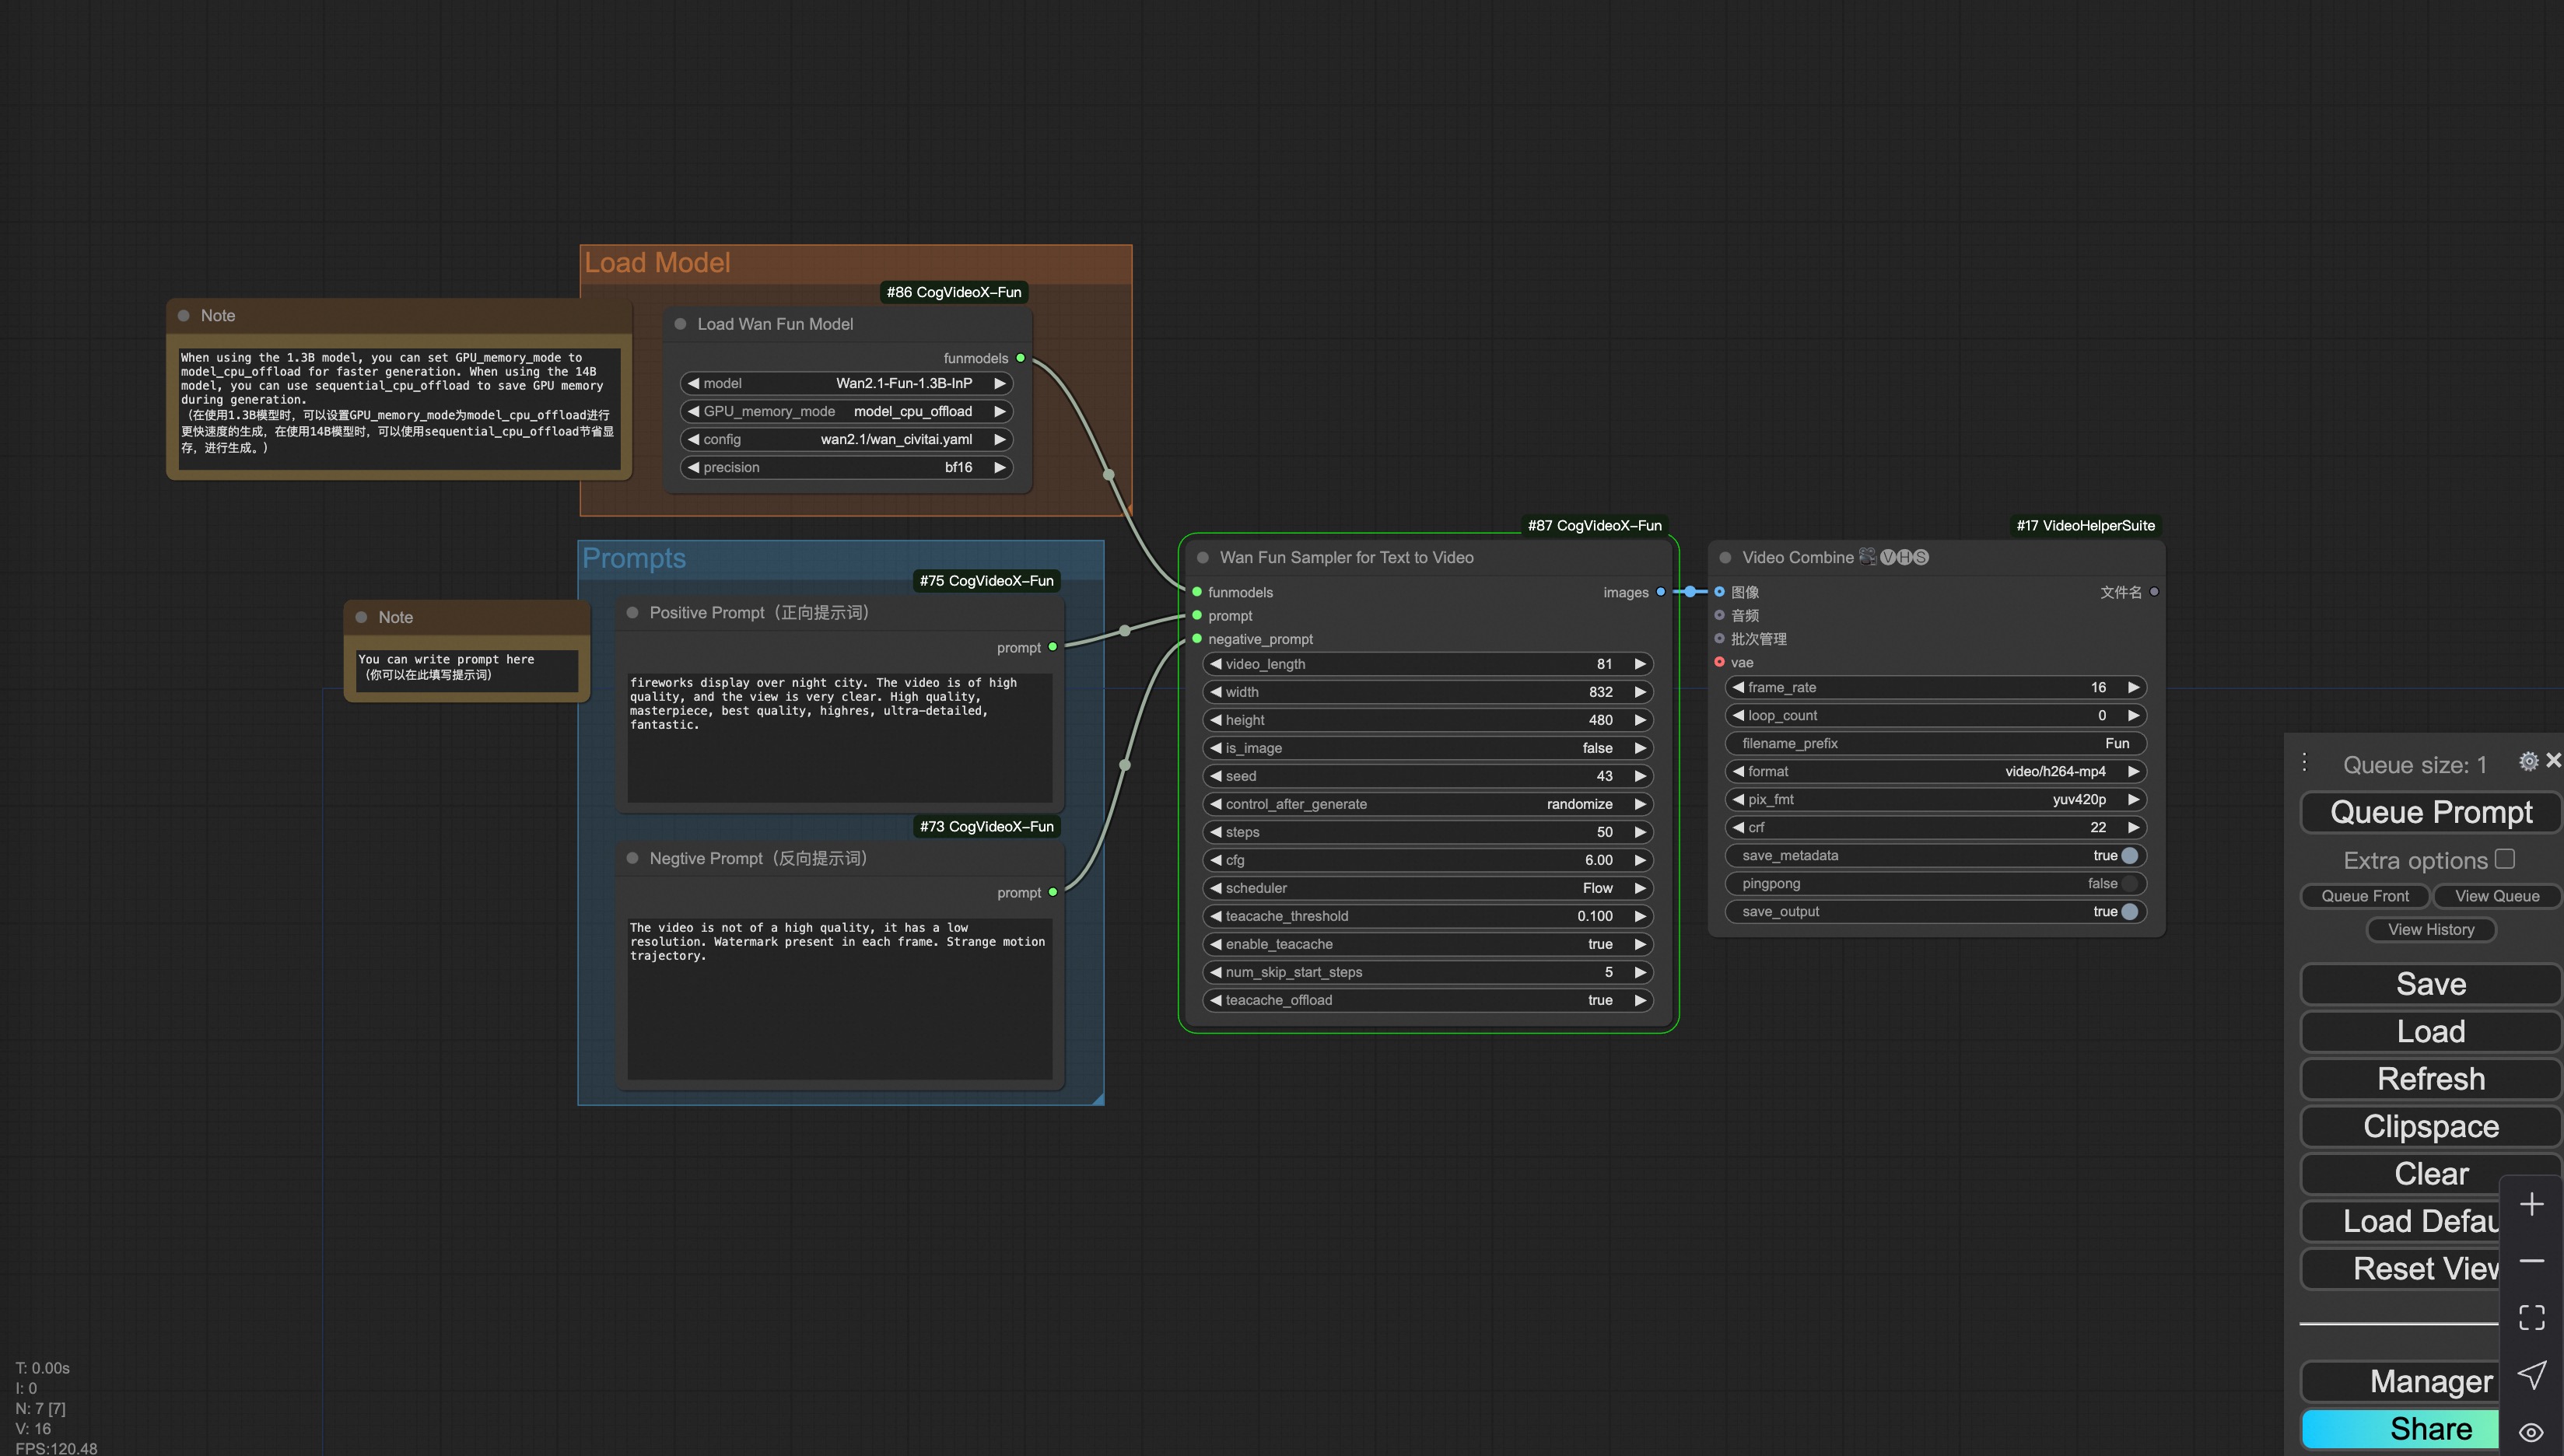
### iii. Trajectory Control Video Generation
-Our user interface is shown as follows, this is the [json](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.0/wan2.1_fun_workflow_control_trajectory.json):
+Our user interface is shown as follows, this is the [json](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_control_trajectory.json):
-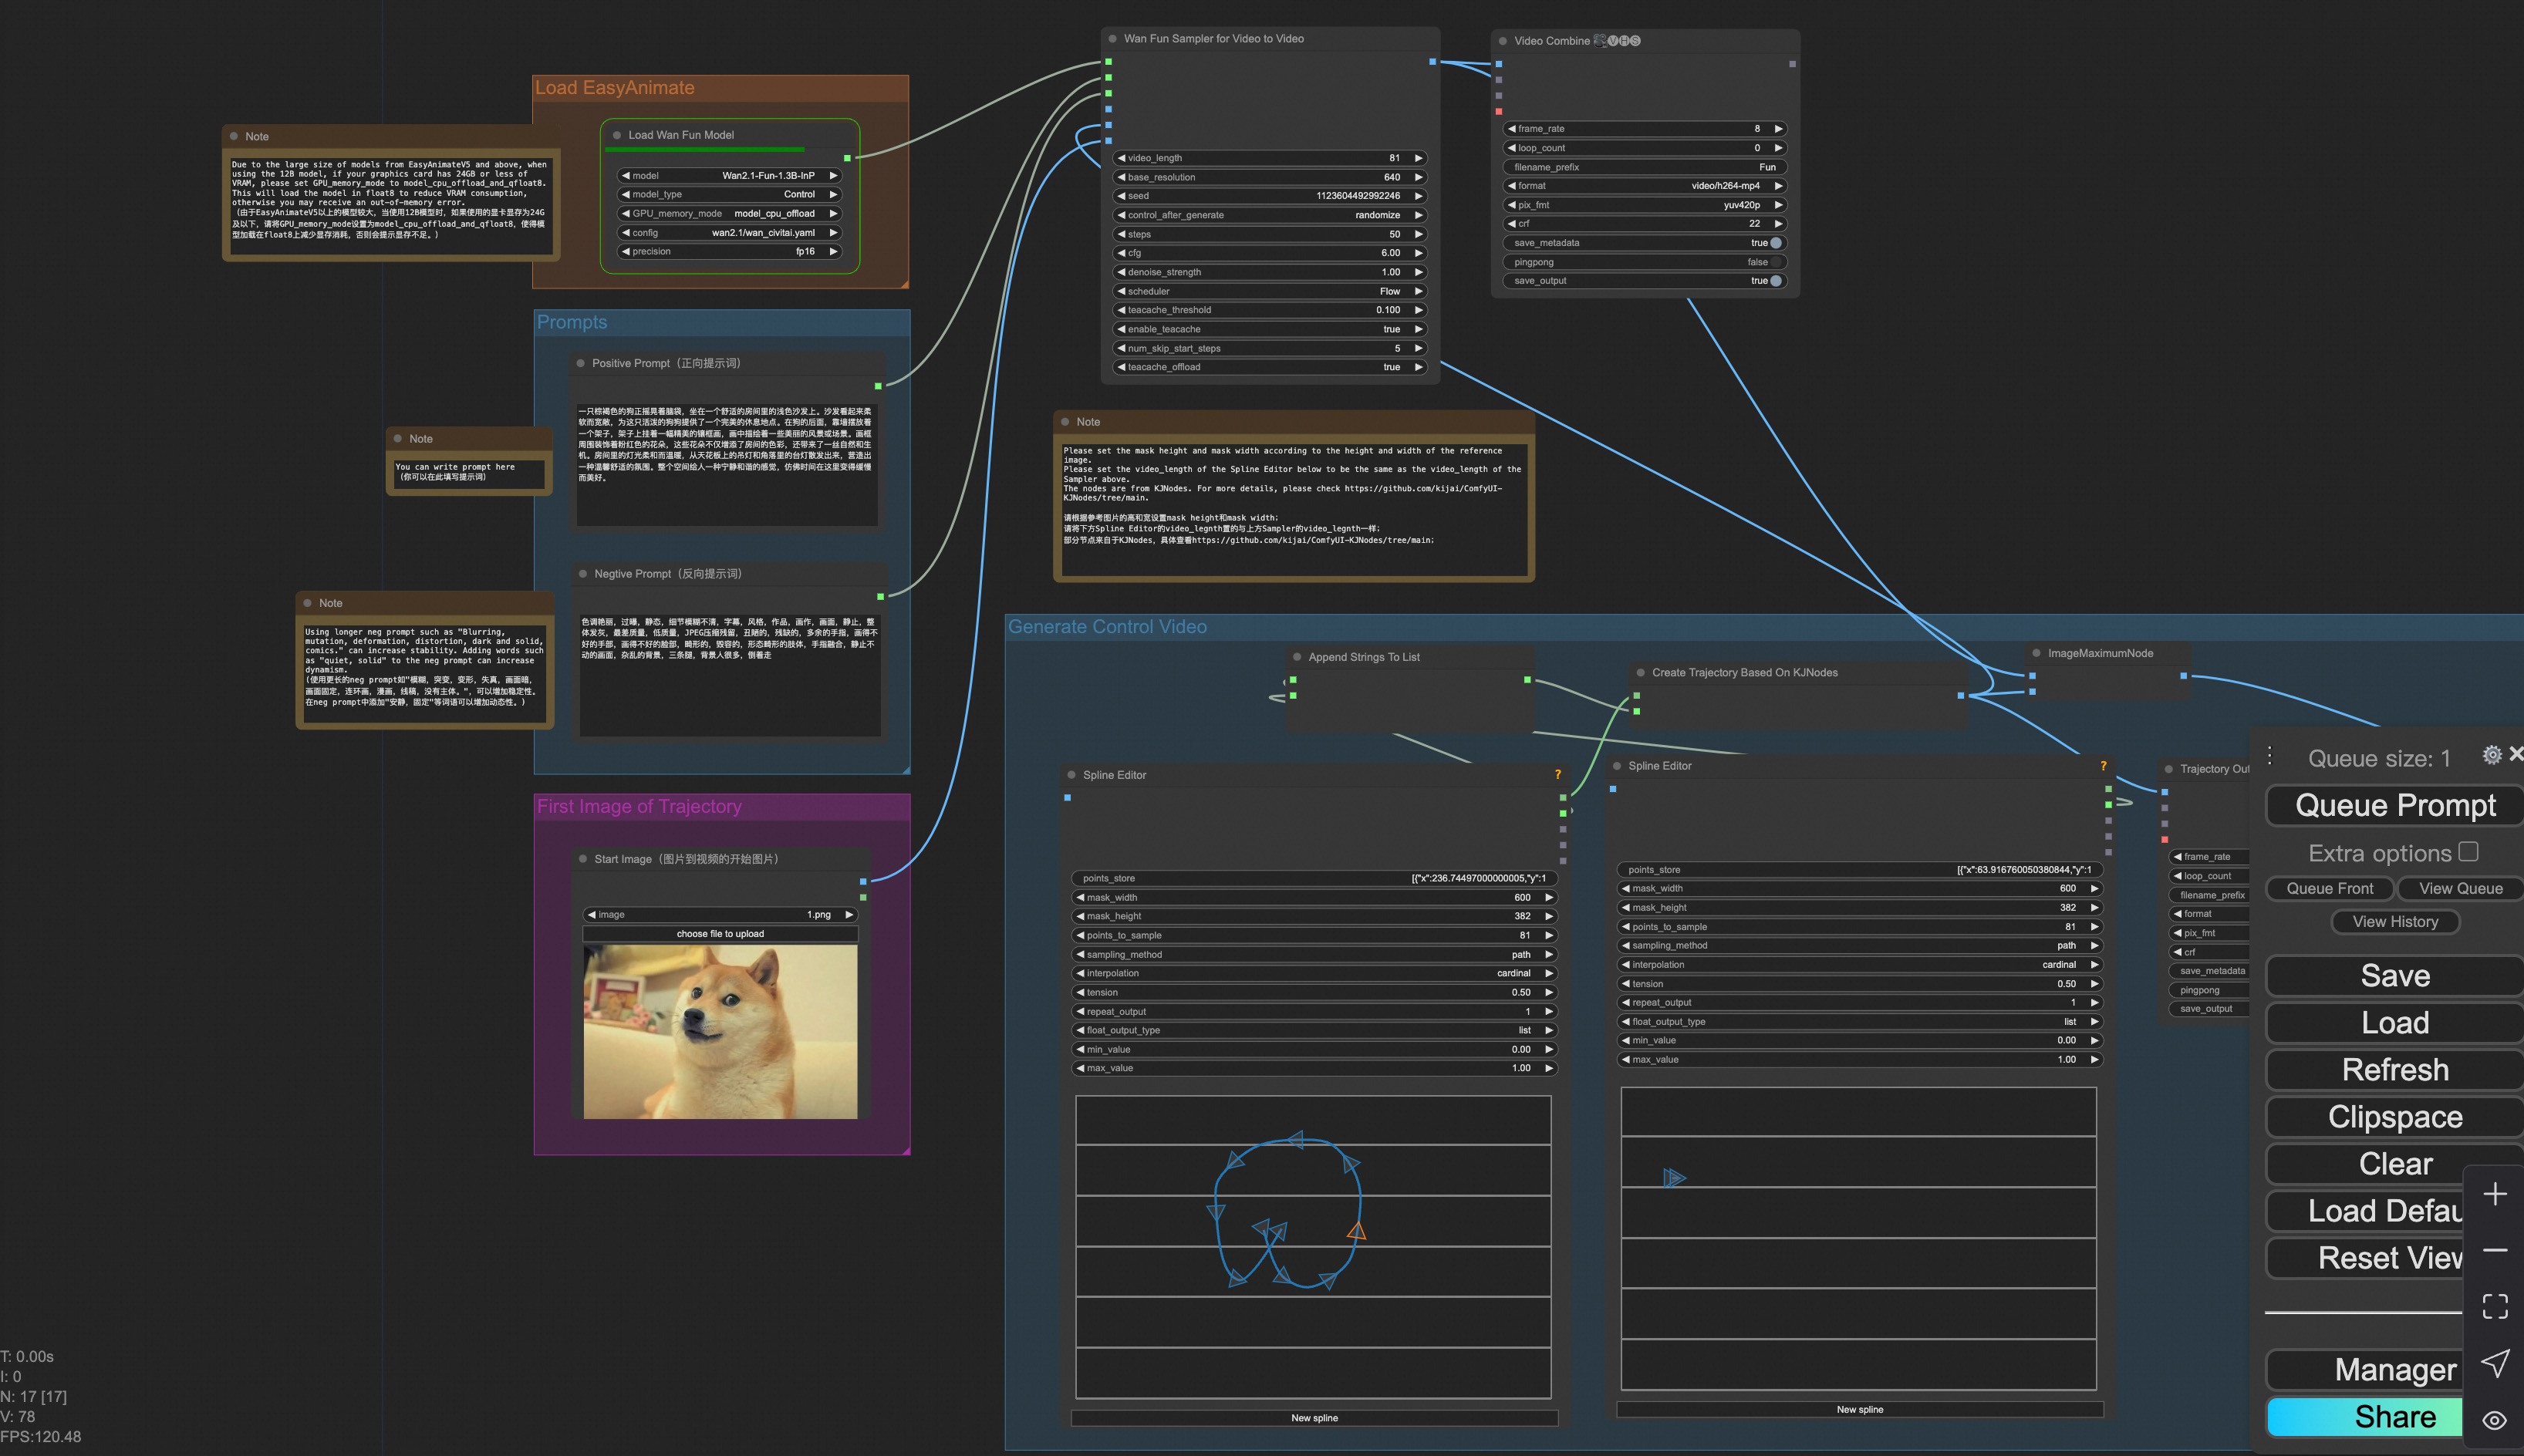
+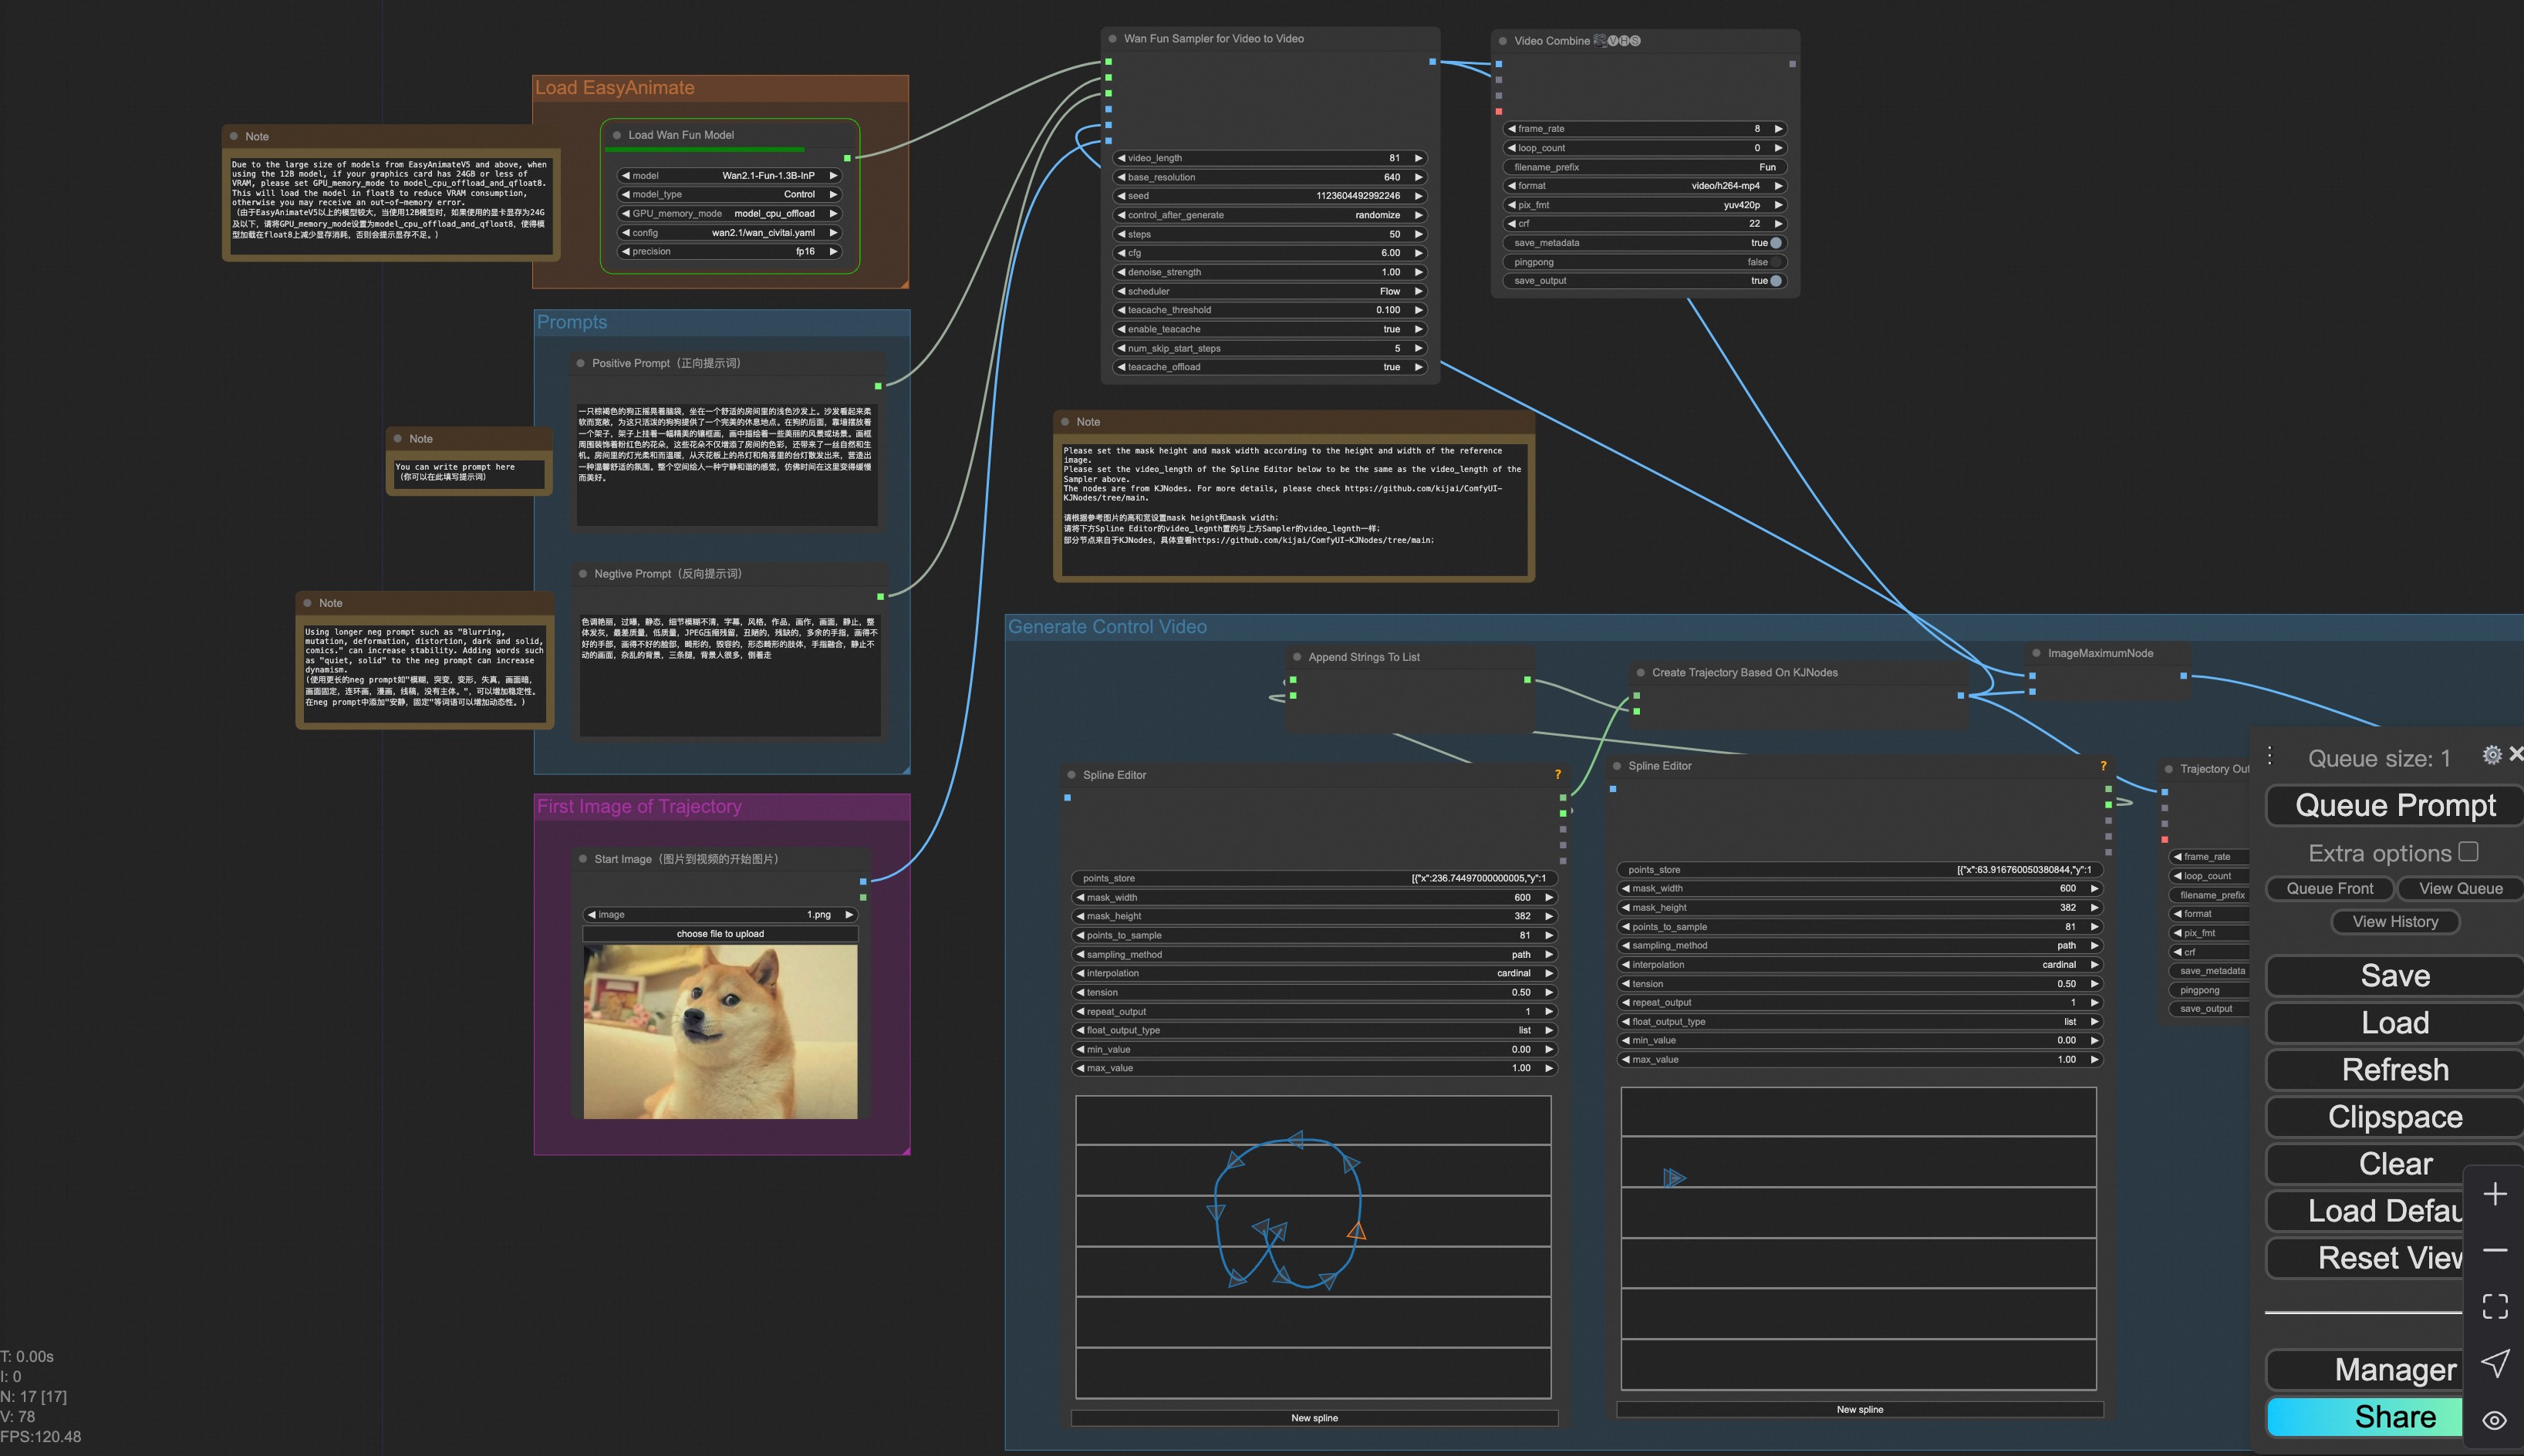
You can run a demo using the following photo:

### iv. Control Video Generation
-Our user interface is shown as follows, this is the [json](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.0/wan2.1_fun_workflow_v2v_control.json):
+Our user interface is shown as follows, this is the [json](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_v2v_control.json):
-To facilitate usage, we have added several JSON configurations that automatically process input videos into the necessary control videos. These include [canny processing](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.0/wan2.1_fun_workflow_v2v_control_canny.json), [pose processing](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.0/wan2.1_fun_workflow_v2v_control_pose.json), and [depth processing](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.0/wan2.1_fun_workflow_v2v_control_depth.json).
+To facilitate usage, we have added several JSON configurations that automatically process input videos into the necessary control videos. These include [canny processing](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_v2v_control_canny.json), [pose processing](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_v2v_control_pose.json), and [depth processing](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_v2v_control_depth.json).
-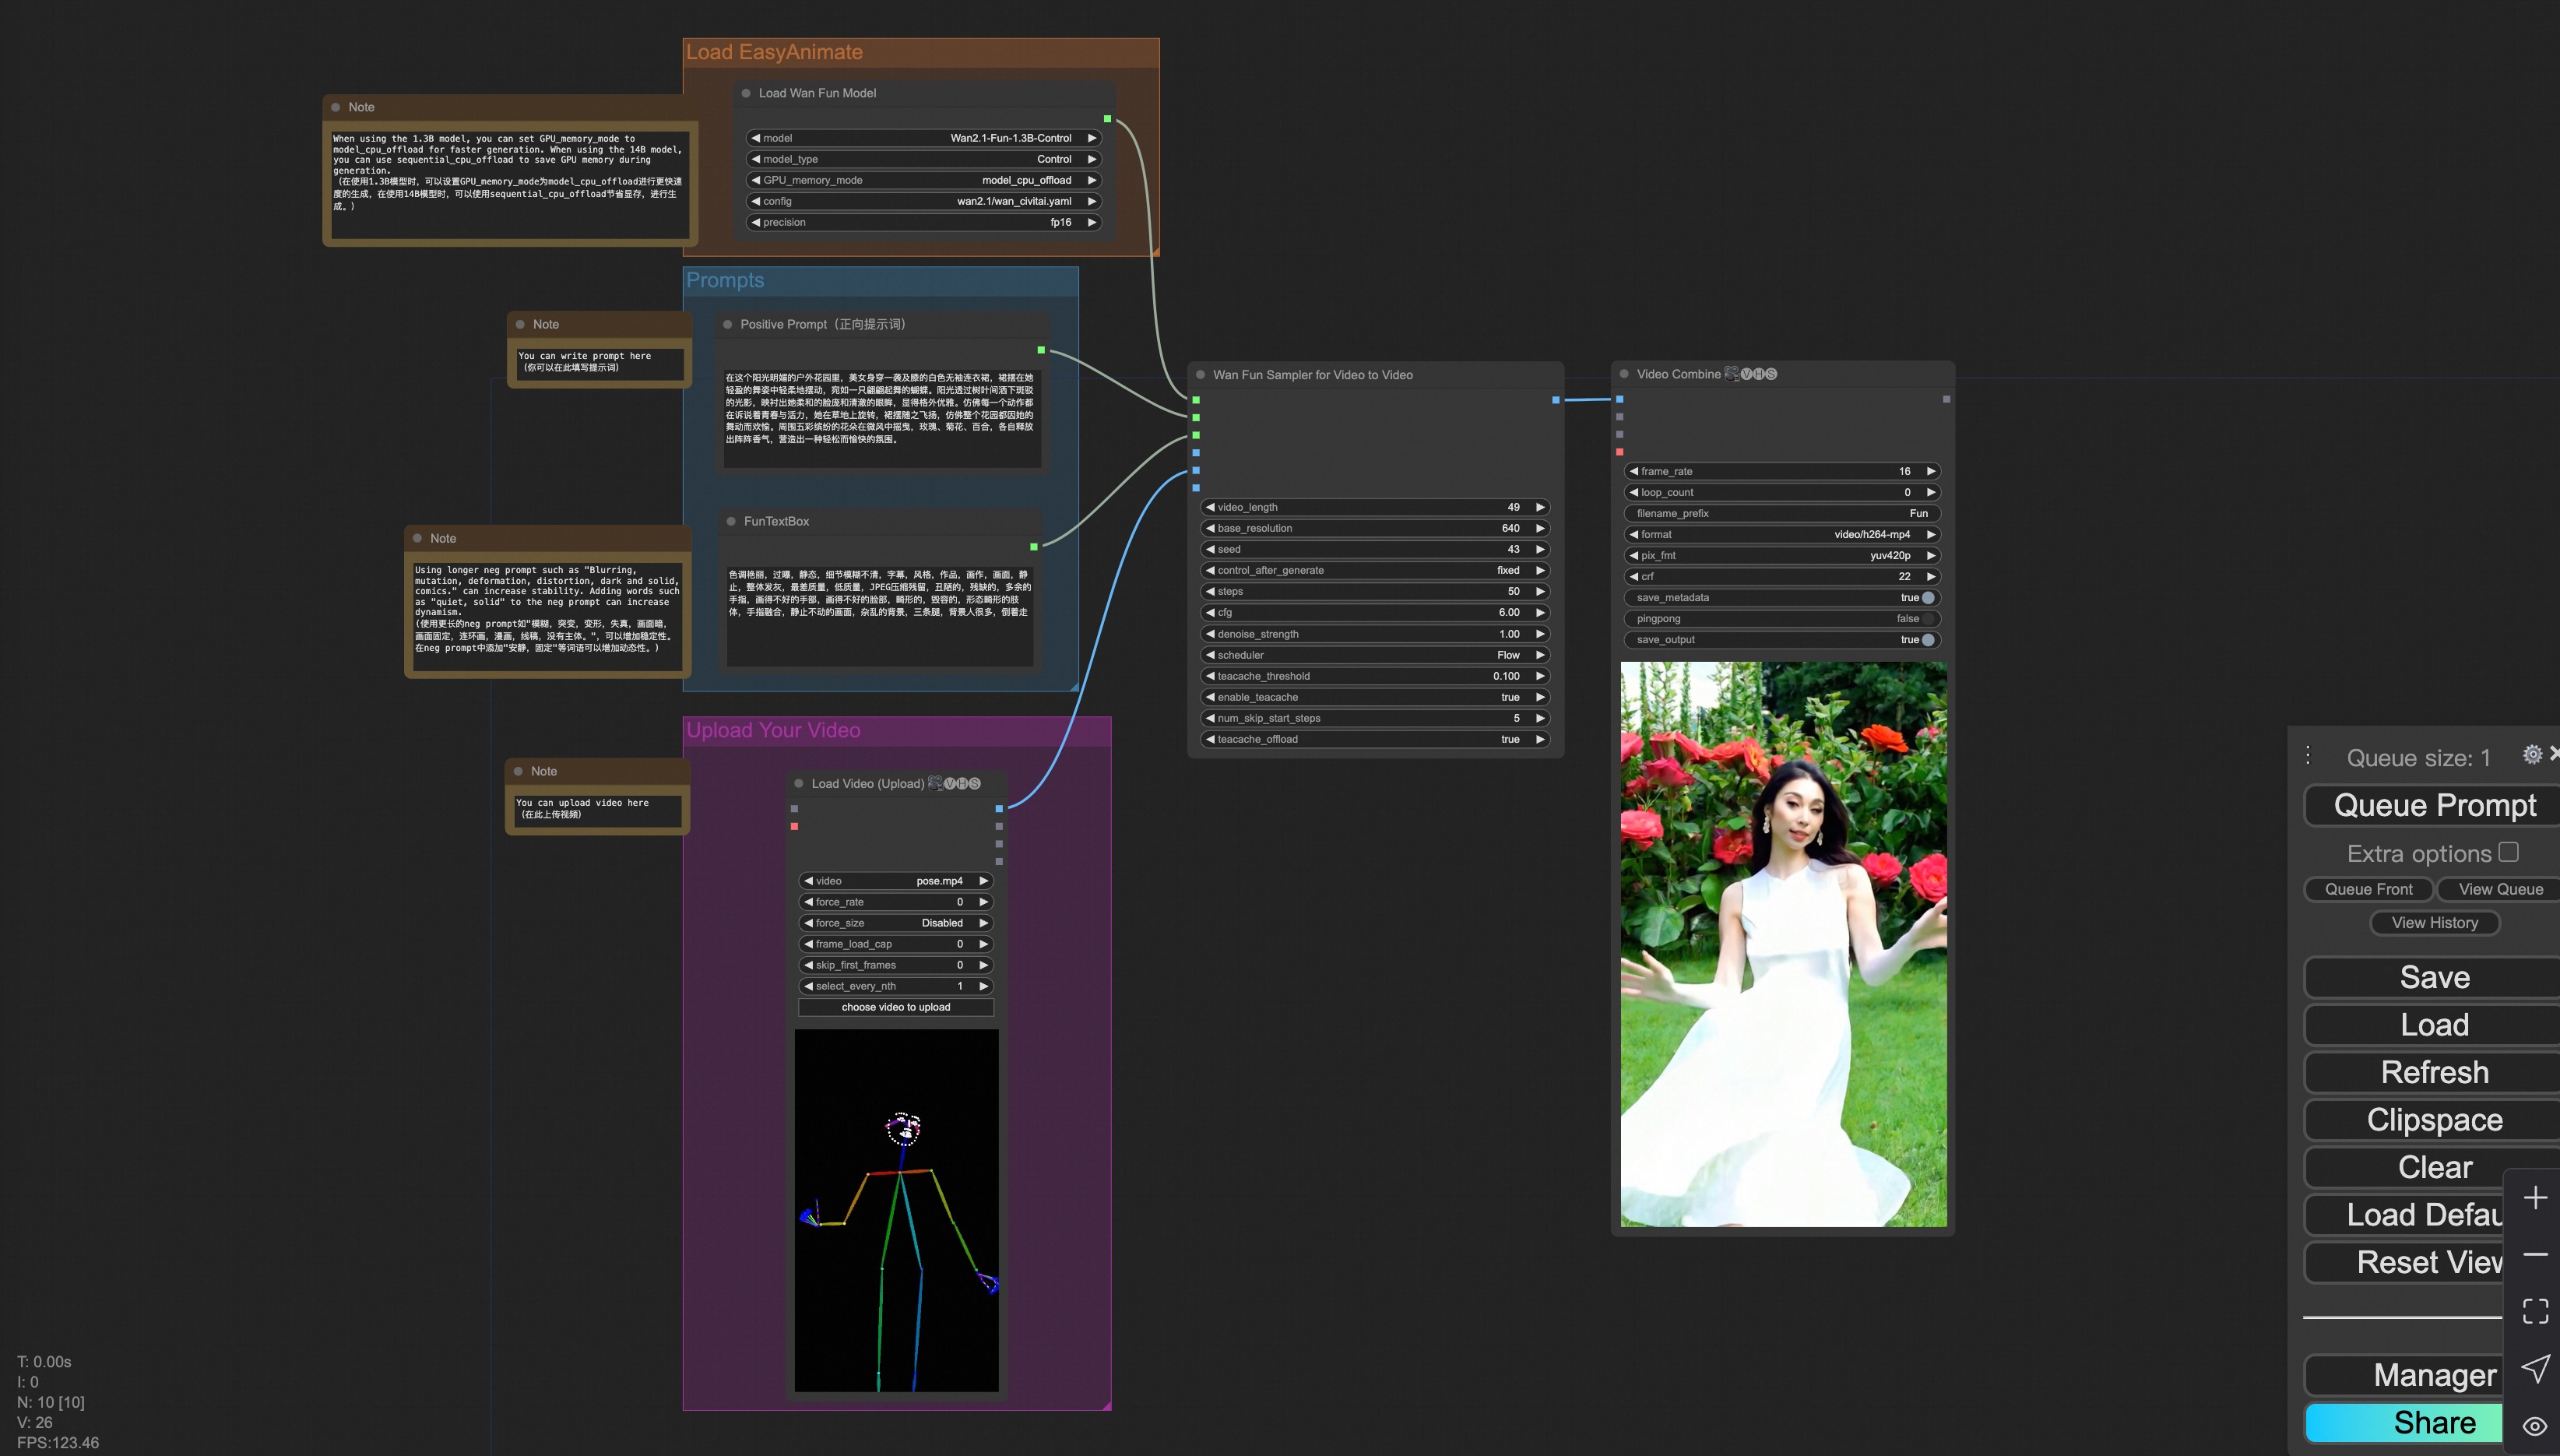
+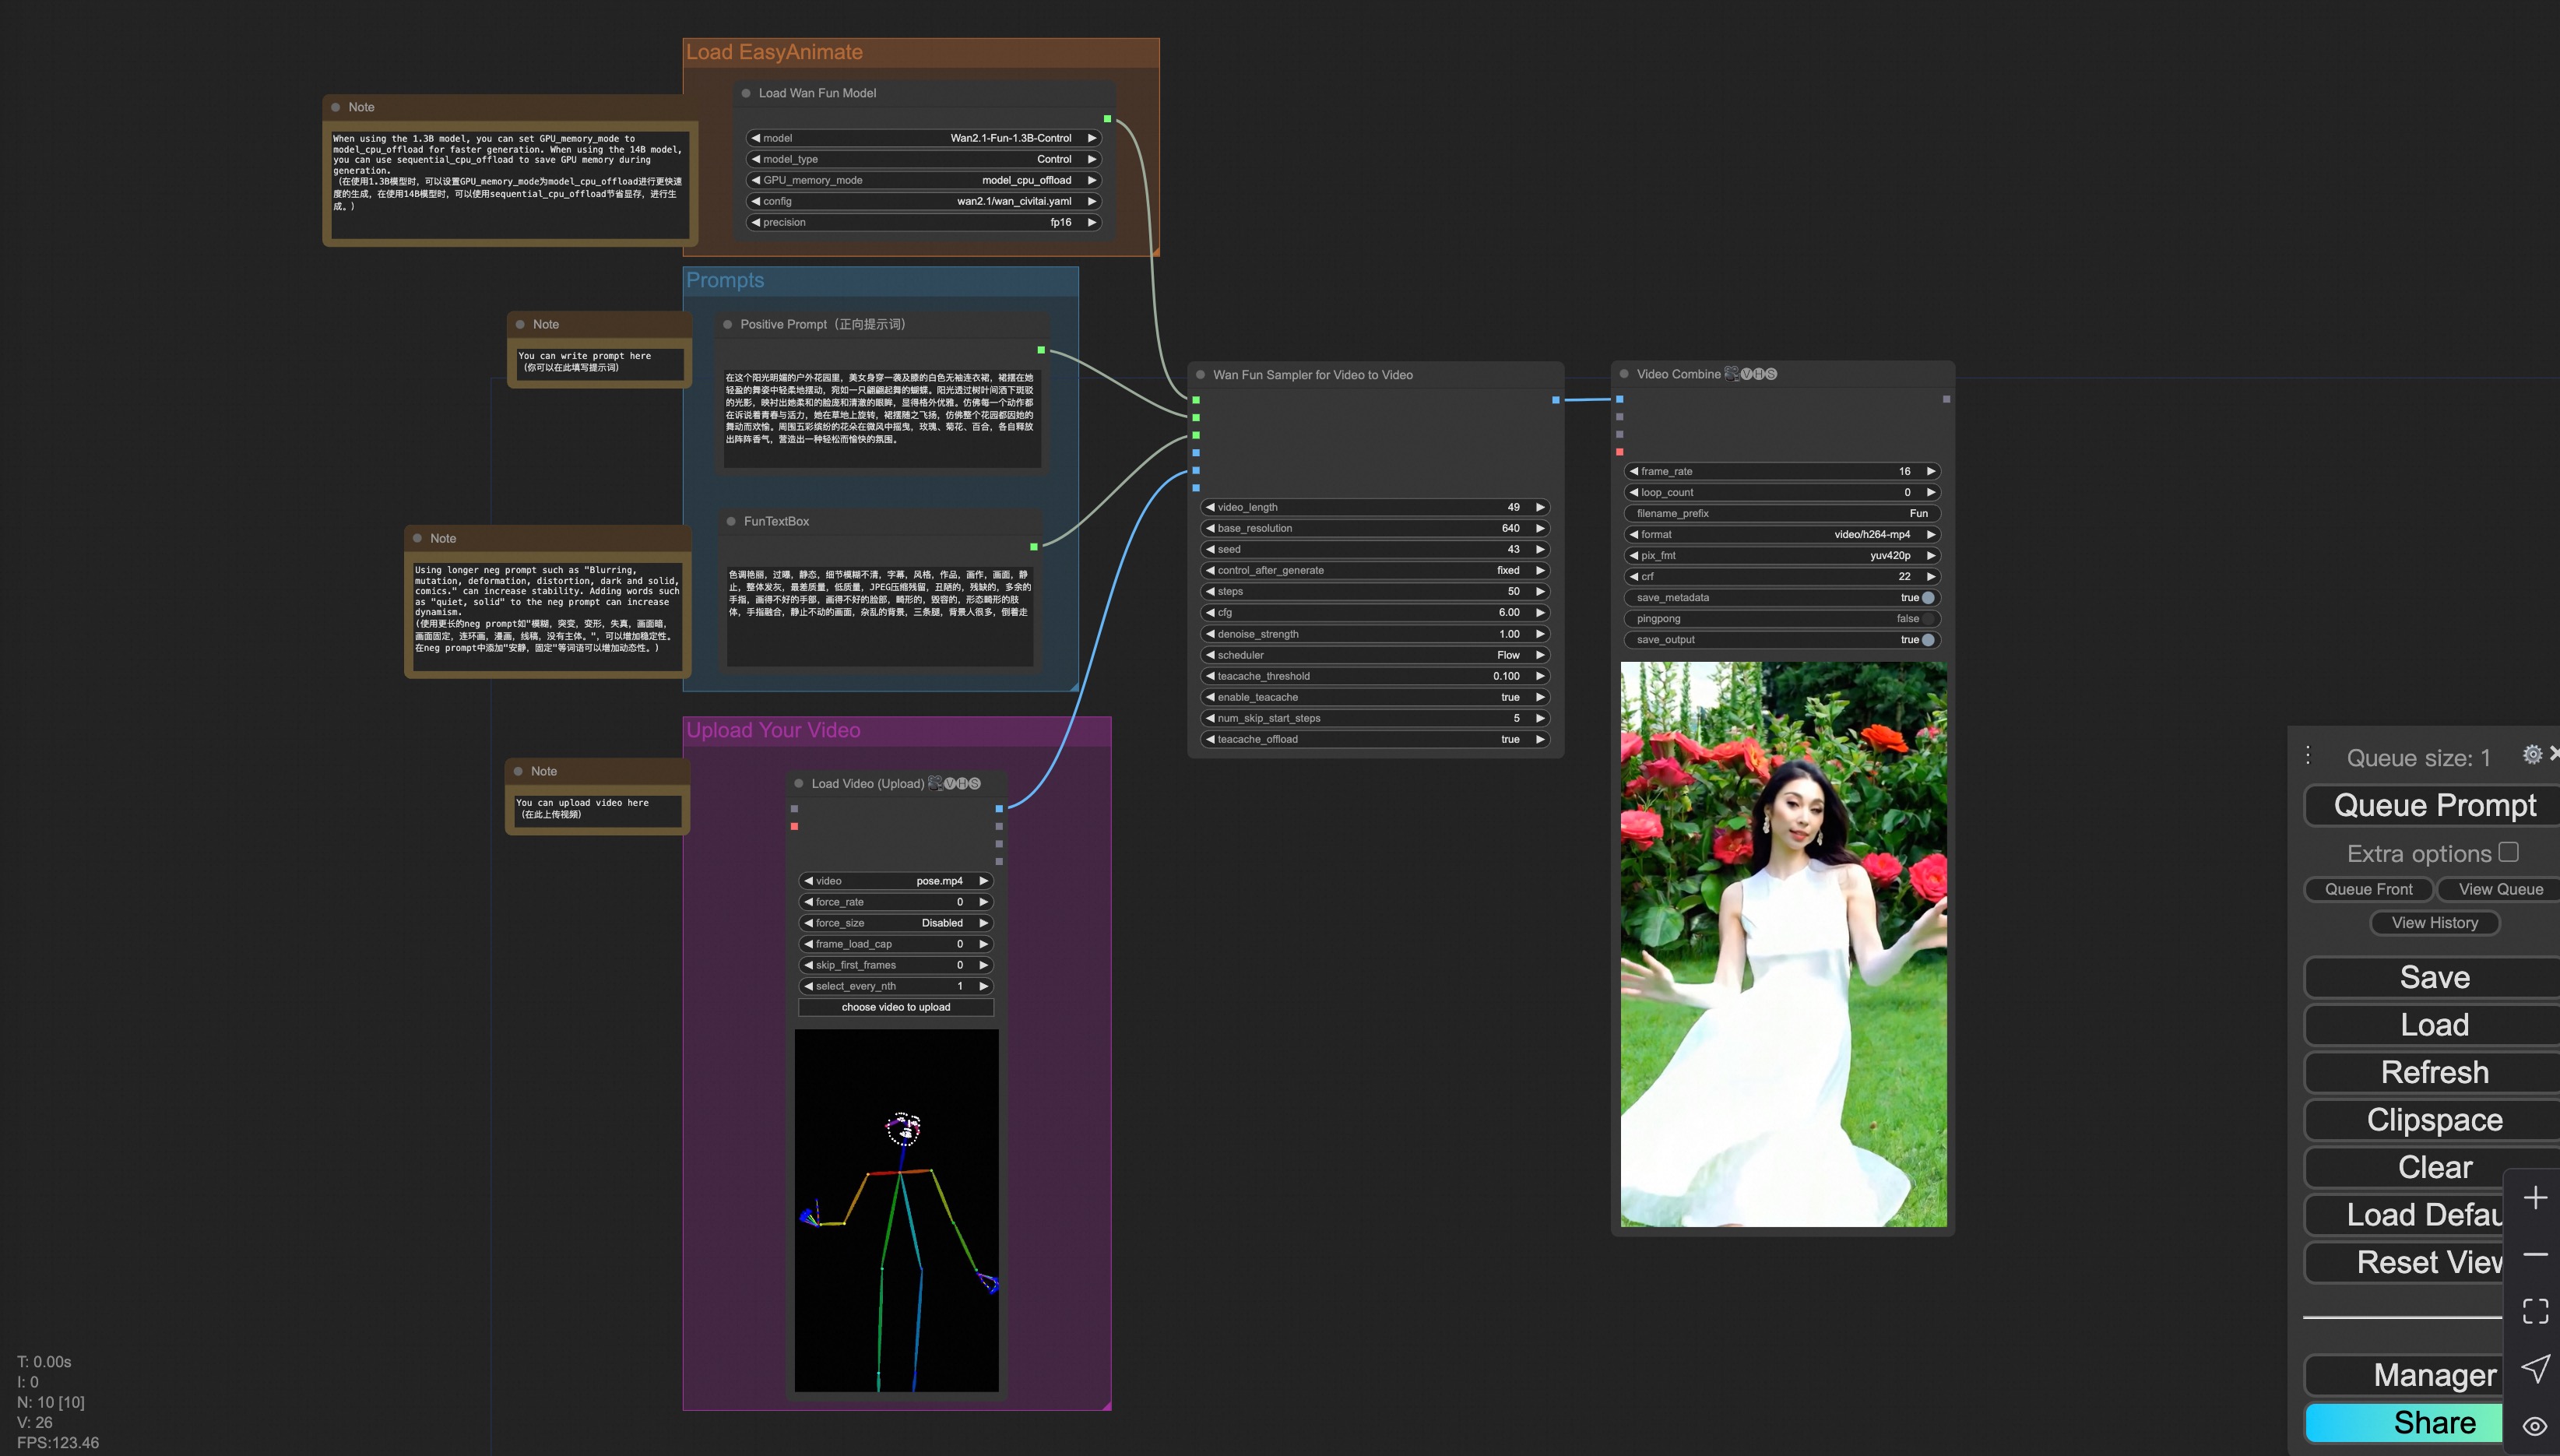
You can run a demo using the following video:
[Demo Video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/pose.mp4)
+### v. Control + Ref Video Generation
+Our user interface is shown as follows, this is the [json](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_v2v_control_ref.json):
+
+To facilitate usage, we have added several JSON configurations that automatically process input videos into the necessary control videos. These include [pose processing](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_v2v_control_pose_ref.json), and [depth processing](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_v2v_control_depth_ref.json).
+
+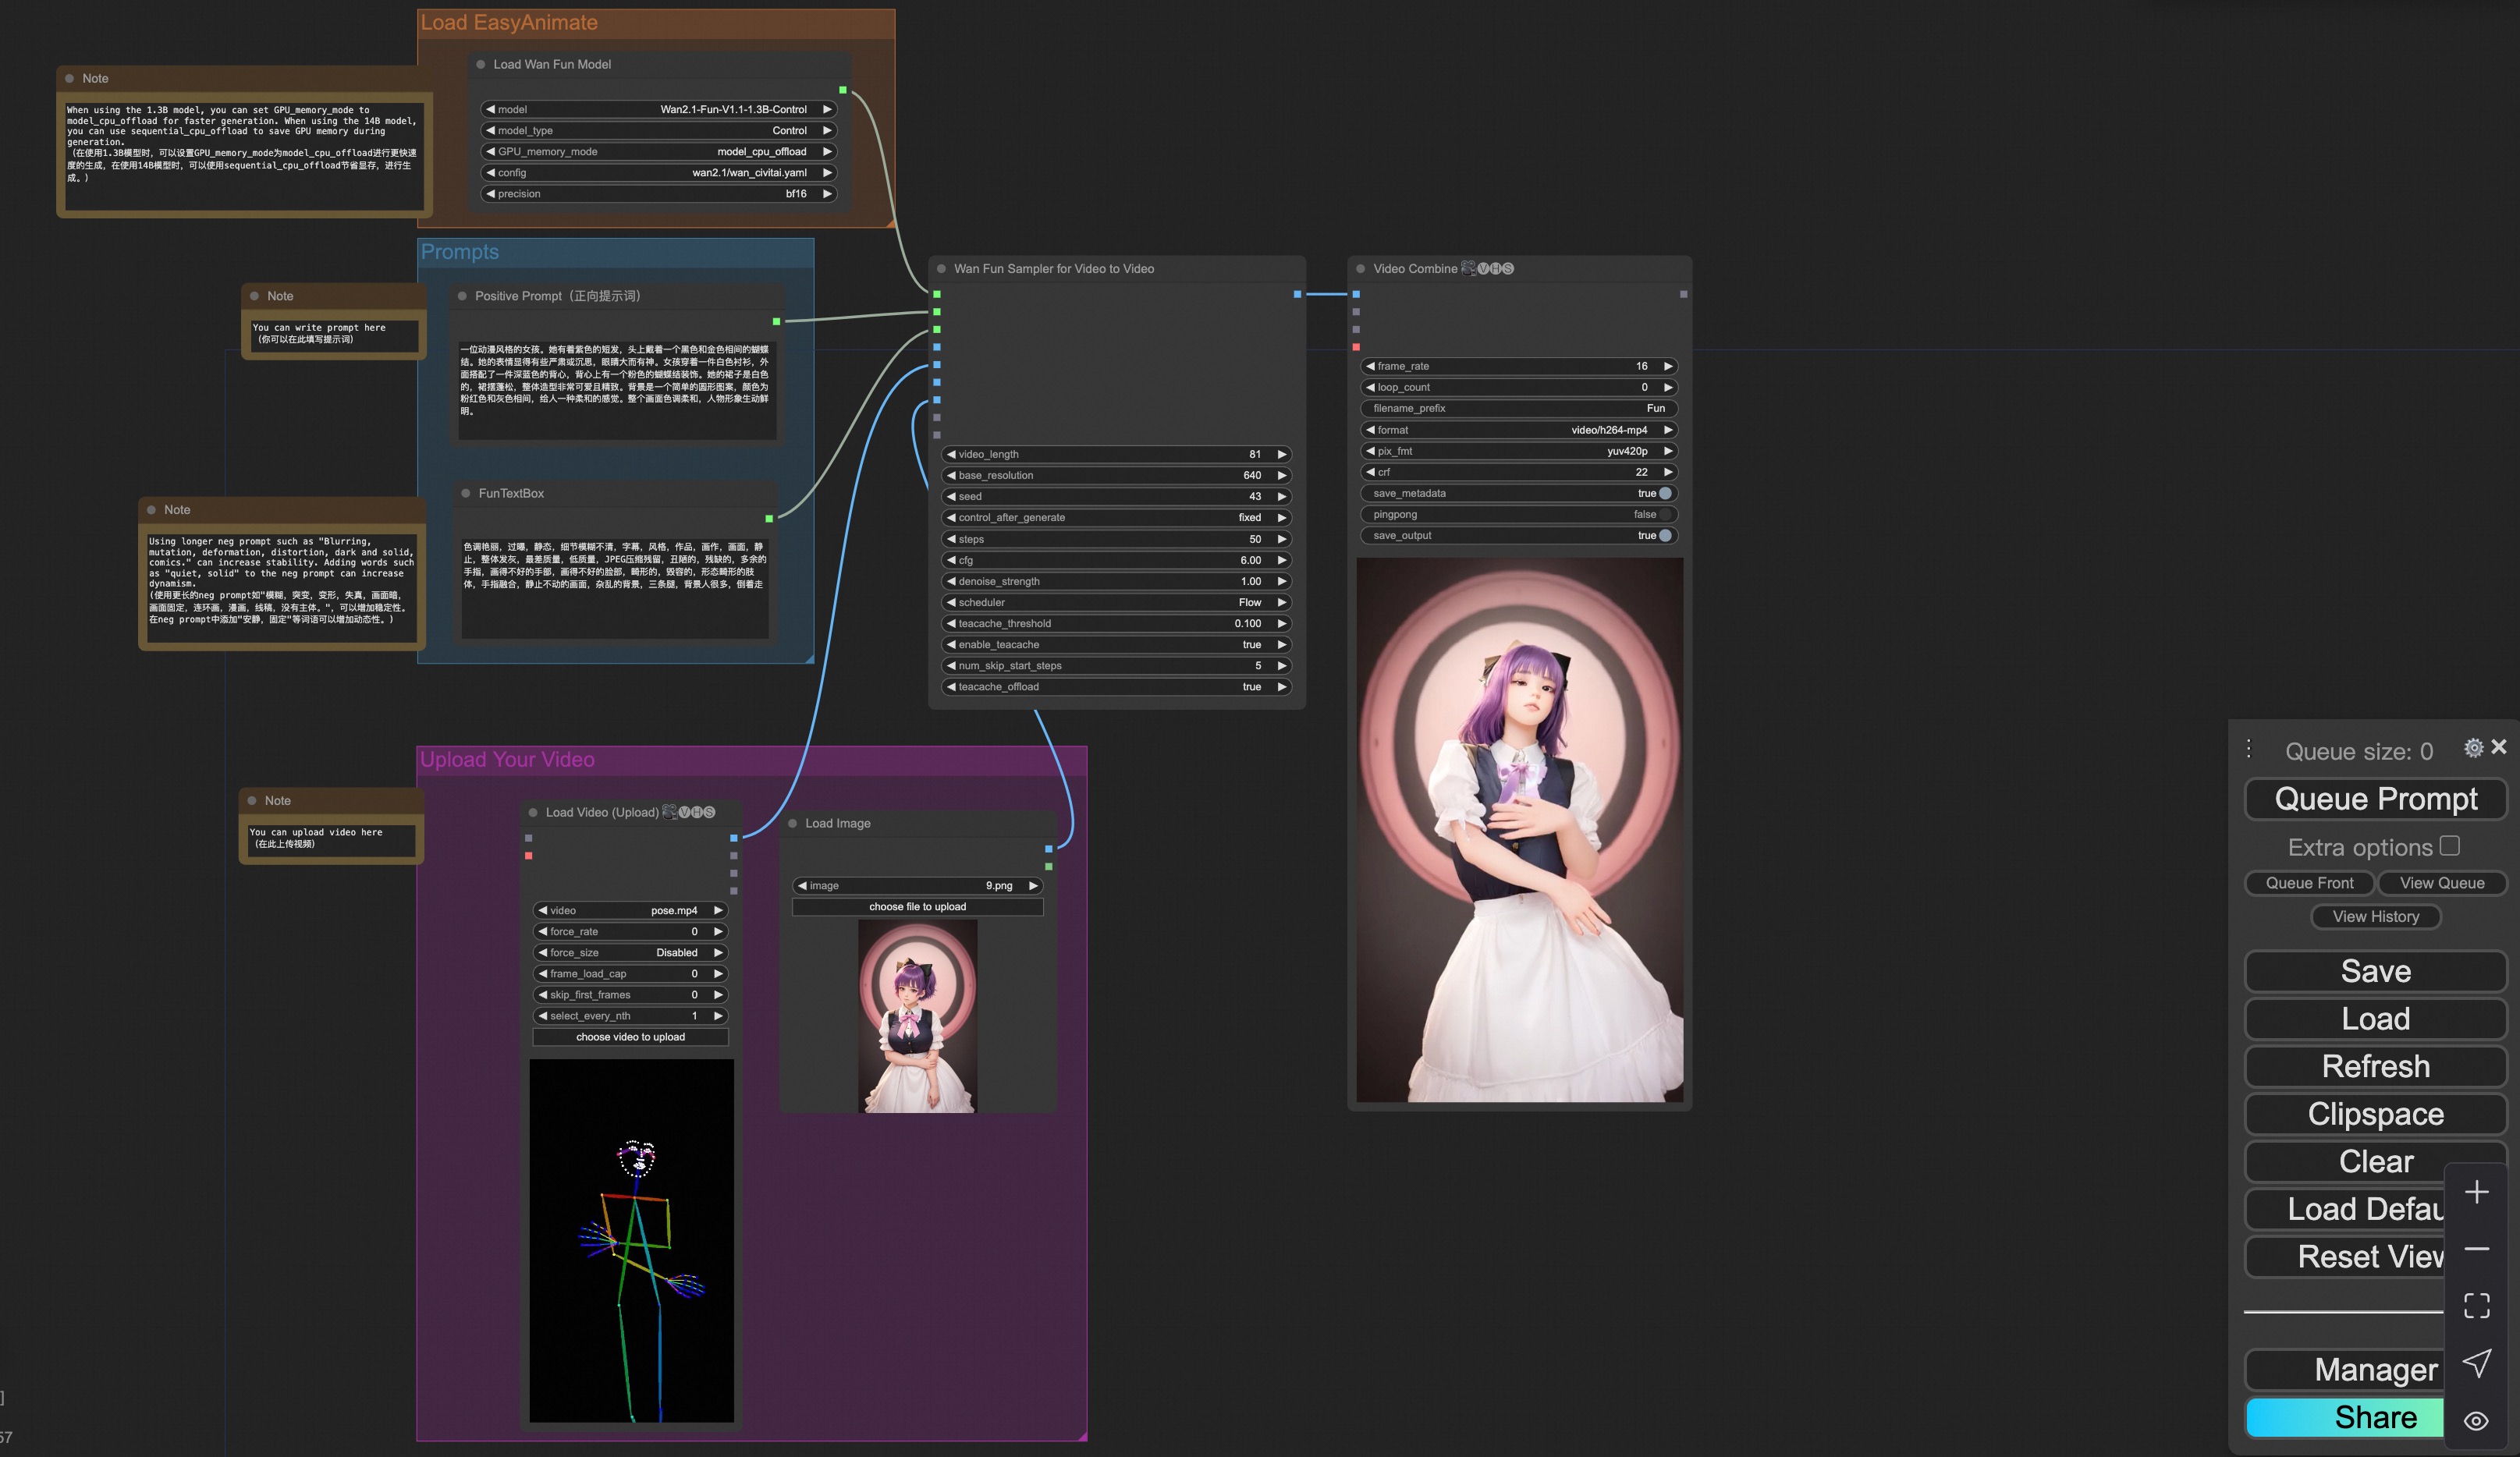
+
+You can run a demo using the following video:
+
+[Demo Image](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/6.png)
+
+[Demo Video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/pose.mp4)
+
+### vi. Camera Control Video Generation
+Our user interface is shown as follows, this is the [json](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan_fun/asset/v1.1/wan2.1_fun_workflow_control_camera.json):
+
+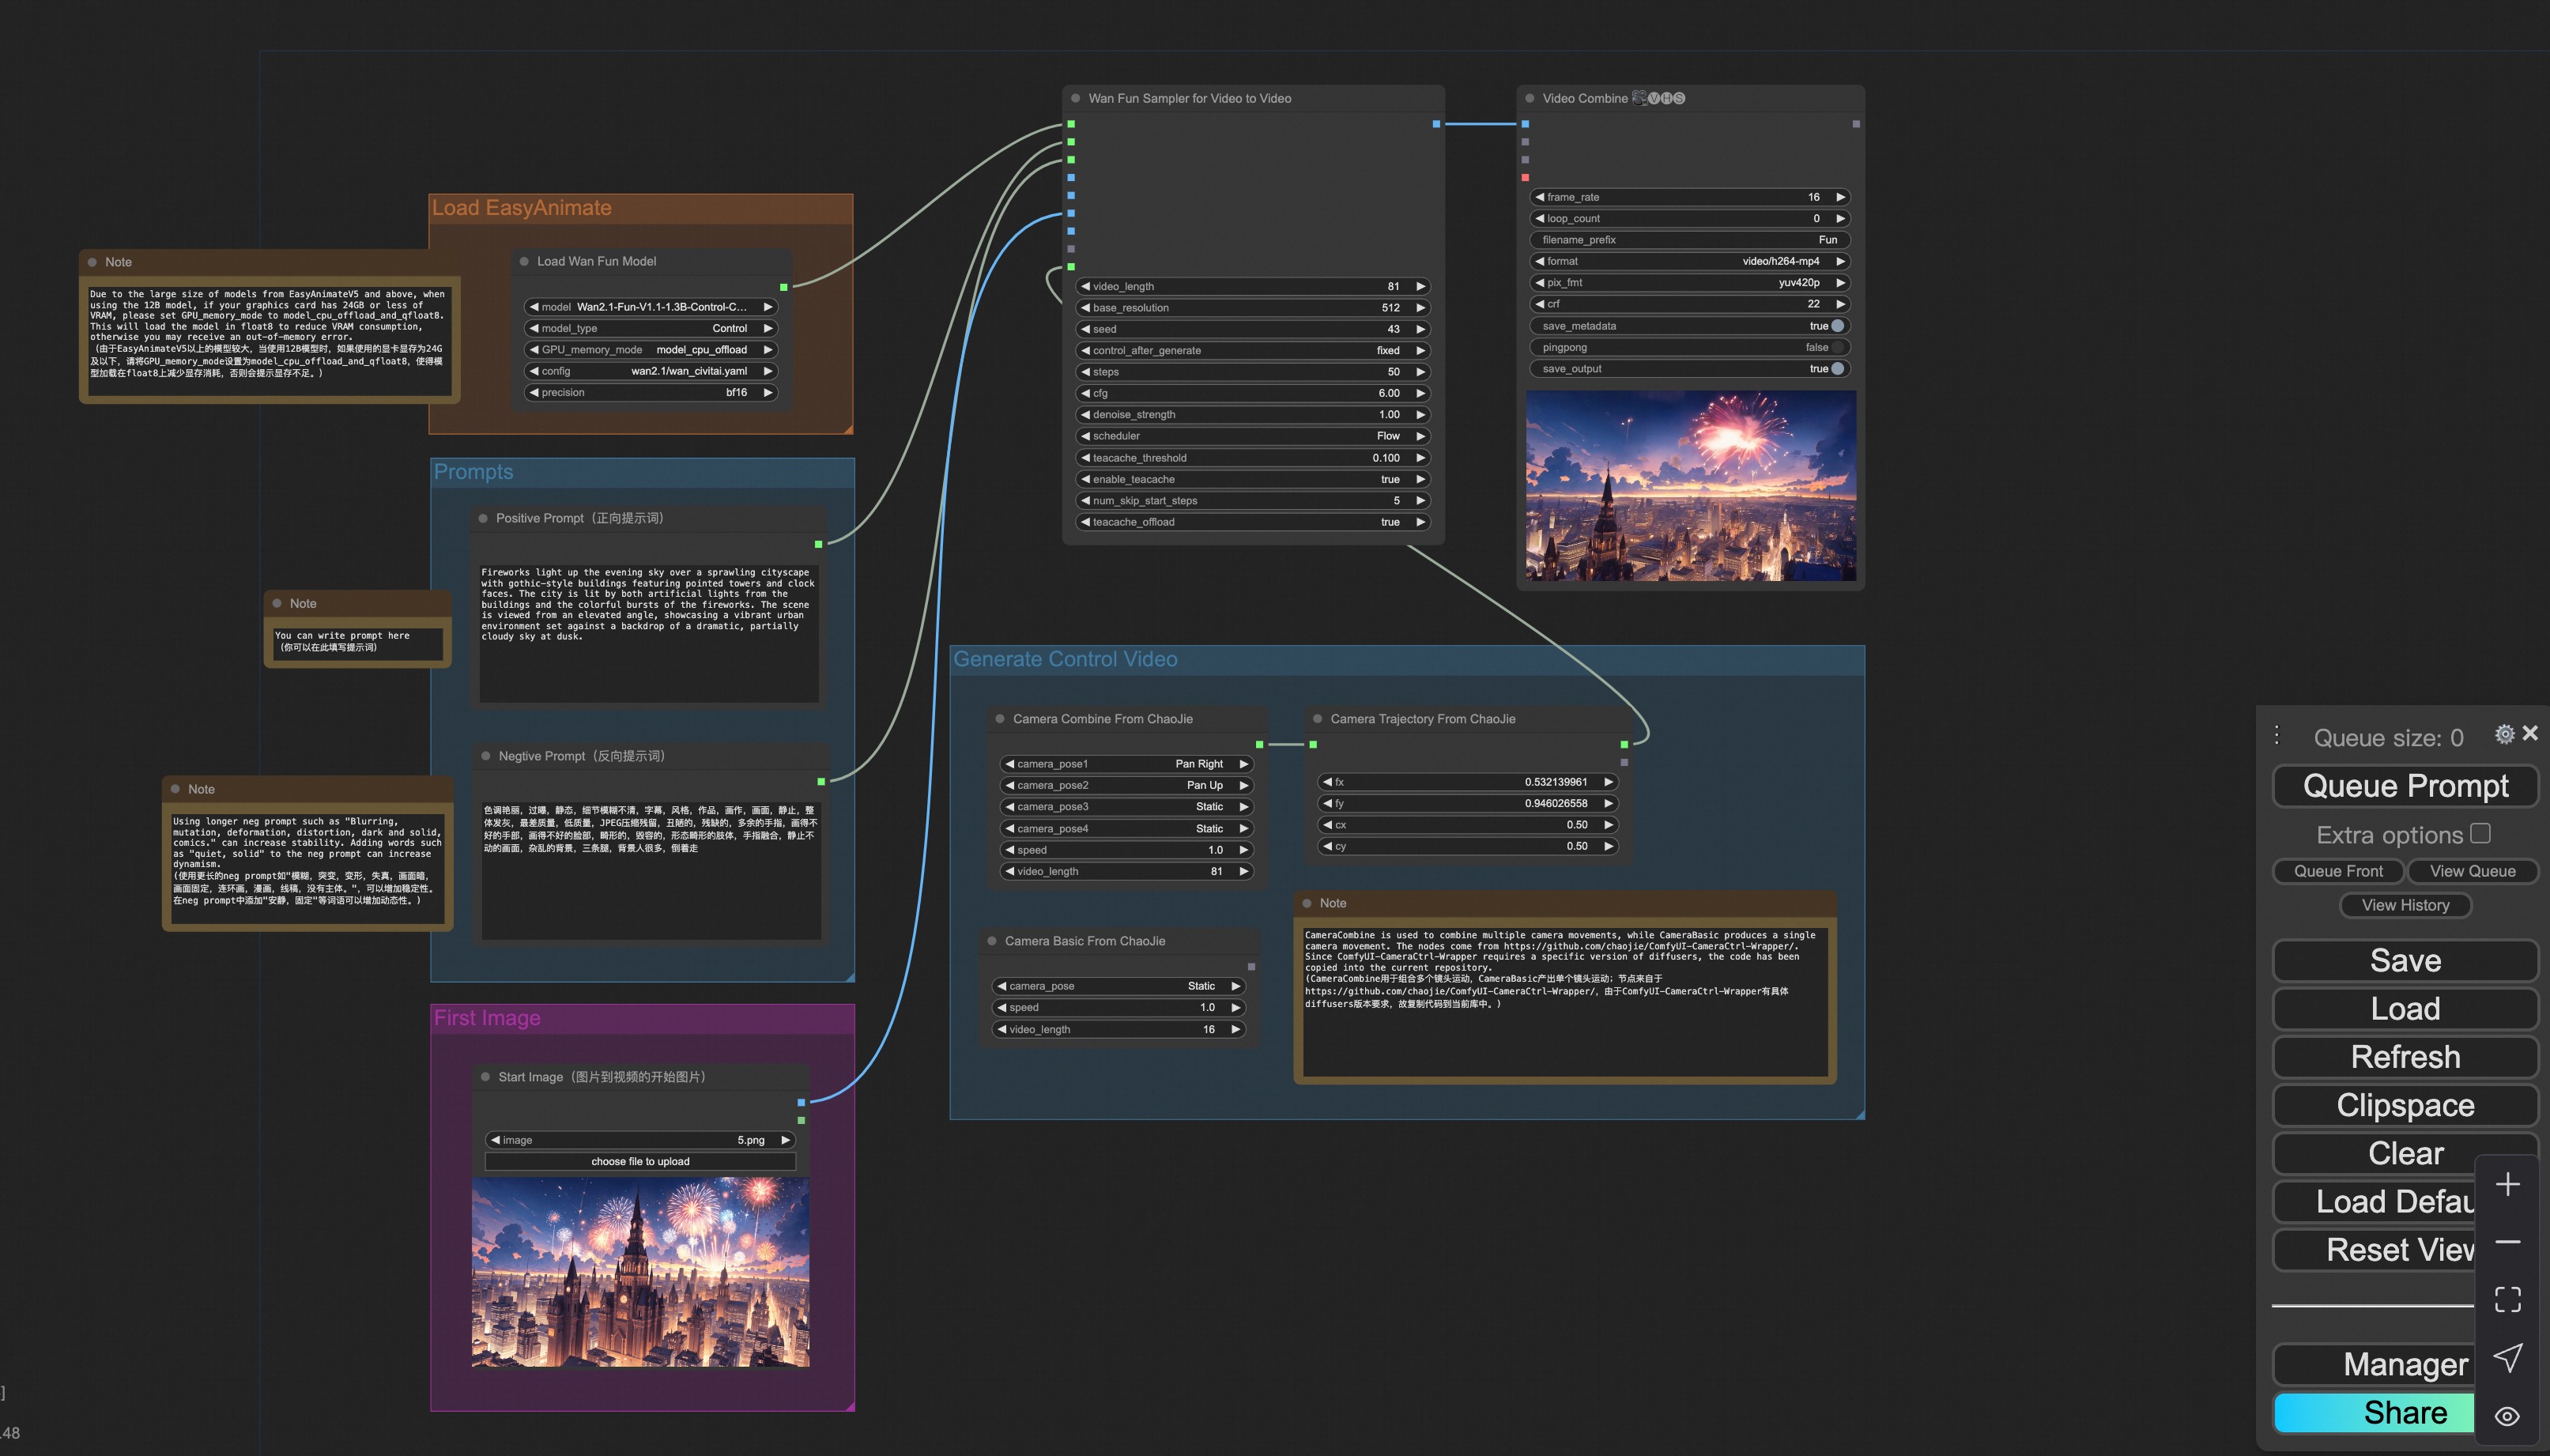
+
+You can run a demo using the following photo:
+
+
+
### 2. Wan
#### i. Image to video generation
[Download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/wan/asset/v1.0/wan2.1_workflow_i2v.json) for wan-fun.
diff --git a/comfyui/camera_utils.py b/comfyui/camera_utils.py
new file mode 100644
index 0000000..efd0558
--- /dev/null
+++ b/comfyui/camera_utils.py
@@ -0,0 +1,80 @@
+"""Modified from https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/blob/main/camera_utils.py
+"""
+import copy
+import numpy as np
+
+CAMERA = {
+ # T
+ "base_T_norm": 1.5,
+ "base_angle": np.pi/3,
+
+ "Static": { "angle":[0., 0., 0.], "T":[0., 0., 0.]},
+ "Pan Up": { "angle":[0., 0., 0.], "T":[0., 1., 0.]},
+ "Pan Down": { "angle":[0., 0., 0.], "T":[0.,-1.,0.]},
+ "Pan Left": { "angle":[0., 0., 0.], "T":[1.,0.,0.]},
+ "Pan Right": { "angle":[0., 0., 0.], "T": [-1.,0.,0.]},
+ "Zoom In": { "angle":[0., 0., 0.], "T": [0.,0.,-2.]},
+ "Zoom Out": { "angle":[0., 0., 0.], "T": [0.,0.,2.]},
+ "ACW": { "angle": [0., 0., 1.], "T":[0., 0., 0.]},
+ "CW": { "angle": [0., 0., -1.], "T":[0., 0., 0.]},
+}
+
+def compute_R_form_rad_angle(angles):
+ theta_x, theta_y, theta_z = angles
+ Rx = np.array([[1, 0, 0],
+ [0, np.cos(theta_x), -np.sin(theta_x)],
+ [0, np.sin(theta_x), np.cos(theta_x)]])
+
+ Ry = np.array([[np.cos(theta_y), 0, np.sin(theta_y)],
+ [0, 1, 0],
+ [-np.sin(theta_y), 0, np.cos(theta_y)]])
+
+ Rz = np.array([[np.cos(theta_z), -np.sin(theta_z), 0],
+ [np.sin(theta_z), np.cos(theta_z), 0],
+ [0, 0, 1]])
+
+ # 计算相机外参的旋转矩阵
+ R = np.dot(Rz, np.dot(Ry, Rx))
+ return R
+
+def get_camera_motion(angle, T, speed, n=16):
+ RT = []
+ for i in range(n):
+ _angle = (i/n)*speed*(CAMERA["base_angle"])*angle
+ R = compute_R_form_rad_angle(_angle)
+ # _T = (i/n)*speed*(T.reshape(3,1))
+ _T=(i/n)*speed*(CAMERA["base_T_norm"])*(T.reshape(3,1))
+ _RT = np.concatenate([R,_T], axis=1)
+ RT.append(_RT)
+ RT = np.stack(RT)
+ return RT
+
+def create_relative(RT_list, K_1=4.7, dataset="syn"):
+ RT = copy.deepcopy(RT_list[0])
+ R_inv = RT[:,:3].T
+ T = RT[:,-1]
+
+ temp = []
+ for _RT in RT_list:
+ _RT[:,:3] = np.dot(_RT[:,:3], R_inv)
+ _RT[:,-1] = _RT[:,-1] - np.dot(_RT[:,:3], T)
+ temp.append(_RT)
+ RT_list = temp
+
+ return RT_list
+
+def combine_camera_motion(RT_0, RT_1):
+ RT = copy.deepcopy(RT_0[-1])
+ R = RT[:,:3]
+ R_inv = RT[:,:3].T
+ T = RT[:,-1]
+
+ temp = []
+ for _RT in RT_1:
+ _RT[:,:3] = np.dot(_RT[:,:3], R)
+ _RT[:,-1] = _RT[:,-1] + np.dot(np.dot(_RT[:,:3], R_inv), T)
+ temp.append(_RT)
+
+ RT_1 = np.stack(temp)
+
+ return np.concatenate([RT_0, RT_1], axis=0)
\ No newline at end of file
diff --git a/comfyui/comfyui_nodes.py b/comfyui/comfyui_nodes.py
index 16567d7..3633544 100755
--- a/comfyui/comfyui_nodes.py
+++ b/comfyui/comfyui_nodes.py
@@ -1,20 +1,21 @@
+import json
+
+import cv2
+import numpy as np
+import torch
+import torch.nn.functional as F
+
+from .annotator.nodes import VideoToCanny, VideoToDepth, VideoToPose
+from .camera_utils import CAMERA, combine_camera_motion, get_camera_motion
from .cogvideox_fun.nodes import (CogVideoXFunInpaintSampler,
CogVideoXFunT2VSampler,
- CogVideoXFunV2VSampler,
- LoadCogVideoXFunLora,
+ CogVideoXFunV2VSampler, LoadCogVideoXFunLora,
LoadCogVideoXFunModel)
-
-from .wan2_1.nodes import (LoadWanModel,
- LoadWanLora,
- WanT2VSampler,
- WanI2VSampler)
-
-from .wan2_1_fun.nodes import (LoadWanFunModel,
- LoadWanFunLora,
- WanFunT2VSampler,
- WanFunInpaintSampler,
- WanFunV2VSampler)
-from .annotator.nodes import VideoToCanny, VideoToDepth, VideoToPose
+from .wan2_1.nodes import (LoadWanLora, LoadWanModel, WanI2VSampler,
+ WanT2VSampler)
+from .wan2_1_fun.nodes import (LoadWanFunLora, LoadWanFunModel,
+ WanFunInpaintSampler, WanFunT2VSampler,
+ WanFunV2VSampler)
class FunTextBox:
@classmethod
@@ -50,6 +51,222 @@ class FunRiflex:
def process(self, riflex_k):
return (riflex_k, )
+def gen_gaussian_heatmap(imgSize=200):
+ circle_img = np.zeros((imgSize, imgSize,), np.float32)
+ circle_mask = cv2.circle(circle_img, (imgSize//2, imgSize//2), imgSize//2 - 1, 1, -1)
+
+ isotropicGrayscaleImage = np.zeros((imgSize, imgSize), np.float32)
+
+ # 生成高斯图
+ for i in range(imgSize):
+ for j in range(imgSize):
+ isotropicGrayscaleImage[i, j] = 1 / (2 * np.pi * (40 ** 2)) * np.exp(
+ -1 / 2 * ((i - imgSize / 2) ** 2 / (40 ** 2) + (j - imgSize / 2) ** 2 / (40 ** 2)))
+
+ isotropicGrayscaleImage = isotropicGrayscaleImage * circle_mask
+ isotropicGrayscaleImage = (isotropicGrayscaleImage / np.max(isotropicGrayscaleImage) * 255).astype(np.uint8)
+ return isotropicGrayscaleImage
+
+class CreateTrajectoryBasedOnKJNodes:
+ # Modified from https://github.com/kijai/ComfyUI-KJNodes/blob/main/nodes/curve_nodes.py
+ # Modify to meet the trajectory control requirements of EasyAnimate.
+ RETURN_TYPES = ("IMAGE", )
+ RETURN_NAMES = ("image", )
+ FUNCTION = "createtrajectory"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "coordinates": ("STRING", {"forceInput": True}),
+ "masks": ("MASK", {"forceInput": True}),
+ },
+ }
+
+ def createtrajectory(self, coordinates, masks):
+ # Define the number of images in the batch
+ if len(coordinates) < 10:
+ coords_list = []
+ for coords in coordinates:
+ coords = json.loads(coords.replace("'", '"'))
+ coords_list.append(coords)
+ else:
+ coords = json.loads(coordinates.replace("'", '"'))
+ coords_list = [coords]
+
+ _, frame_height, frame_width = masks.size()
+ heatmap = gen_gaussian_heatmap()
+
+ circle_size = int(50 * ((frame_height * frame_width) / (1280 * 720)) ** (1/2))
+
+ images_list = []
+ for coords in coords_list:
+ _images_list = []
+ for i in range(len(coords)):
+ _image = np.zeros((frame_height, frame_width, 3))
+ center_coordinate = [coords[i][key] for key in coords[i]]
+
+ y1 = max(center_coordinate[1] - circle_size, 0)
+ y2 = min(center_coordinate[1] + circle_size, np.shape(_image)[0] - 1)
+ x1 = max(center_coordinate[0] - circle_size, 0)
+ x2 = min(center_coordinate[0] + circle_size, np.shape(_image)[1] - 1)
+
+ if x2 - x1 > 3 and y2 - y1 > 3:
+ need_map = cv2.resize(heatmap, (x2 - x1, y2 - y1))[:, :, None]
+ _image[y1:y2, x1:x2] = np.maximum(need_map.copy(), _image[y1:y2, x1:x2])
+
+ _image = np.expand_dims(_image, 0) / 255
+ _images_list.append(_image)
+ images_list.append(np.concatenate(_images_list, axis=0))
+
+ out_images = torch.from_numpy(np.max(np.array(images_list), axis=0))
+ return (out_images, )
+
+class ImageMaximumNode:
+ RETURN_TYPES = ("IMAGE", )
+ RETURN_NAMES = ("image", )
+ FUNCTION = "imagemaximum"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "video_1": ("IMAGE",),
+ "video_2": ("IMAGE",),
+ },
+ }
+
+ def imagemaximum(self, video_1, video_2):
+ length_1, h_1, w_1, c_1 = video_1.size()
+ length_2, h_2, w_2, c_2 = video_2.size()
+
+ if h_1 != h_2 or w_1 != w_2:
+ video_1, video_2 = video_1.permute([0, 3, 1, 2]), video_2.permute([0, 3, 1, 2])
+ video_2 = F.interpolate(video_2, video_1.size()[-2:])
+ video_1, video_2 = video_1.permute([0, 2, 3, 1]), video_2.permute([0, 2, 3, 1])
+
+ if length_1 > length_2:
+ outputs = torch.maximum(video_1[:length_2], video_2)
+ else:
+ outputs = torch.maximum(video_1, video_2[:length_1])
+ return (outputs, )
+
+class CameraBasicFromChaoJie:
+ # Copied from https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/blob/main/nodes.py
+ # Since ComfyUI-CameraCtrl-Wrapper requires a specific version of diffusers, which is not suitable for us.
+ # The code has been copied into the current repository.
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "camera_pose":(["Static","Pan Up","Pan Down","Pan Left","Pan Right","Zoom In","Zoom Out","ACW","CW"],{"default":"Static"}),
+ "speed":("FLOAT",{"default":1.0}),
+ "video_length":("INT",{"default":16}),
+ },
+ }
+
+ RETURN_TYPES = ("CameraPose",)
+ FUNCTION = "run"
+ CATEGORY = "CameraCtrl"
+
+ def run(self,camera_pose,speed,video_length):
+ camera_dict = {
+ "motion":[camera_pose],
+ "mode": "Basic Camera Poses", # "First A then B", "Both A and B", "Custom"
+ "speed": speed,
+ "complex": None
+ }
+ motion_list = camera_dict['motion']
+ mode = camera_dict['mode']
+ speed = camera_dict['speed']
+ angle = np.array(CAMERA[motion_list[0]]["angle"])
+ T = np.array(CAMERA[motion_list[0]]["T"])
+ RT = get_camera_motion(angle, T, speed, video_length)
+ return (RT,)
+
+class CameraCombineFromChaoJie:
+ # Copied from https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/blob/main/nodes.py
+ # Since ComfyUI-CameraCtrl-Wrapper requires a specific version of diffusers, which is not suitable for us.
+ # The code has been copied into the current repository.
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "camera_pose1":(["Static","Pan Up","Pan Down","Pan Left","Pan Right","Zoom In","Zoom Out","ACW","CW"],{"default":"Static"}),
+ "camera_pose2":(["Static","Pan Up","Pan Down","Pan Left","Pan Right","Zoom In","Zoom Out","ACW","CW"],{"default":"Static"}),
+ "camera_pose3":(["Static","Pan Up","Pan Down","Pan Left","Pan Right","Zoom In","Zoom Out","ACW","CW"],{"default":"Static"}),
+ "camera_pose4":(["Static","Pan Up","Pan Down","Pan Left","Pan Right","Zoom In","Zoom Out","ACW","CW"],{"default":"Static"}),
+ "speed":("FLOAT",{"default":1.0}),
+ "video_length":("INT",{"default":16}),
+ },
+ }
+
+ RETURN_TYPES = ("CameraPose",)
+ FUNCTION = "run"
+ CATEGORY = "CameraCtrl"
+
+ def run(self,camera_pose1,camera_pose2,camera_pose3,camera_pose4,speed,video_length):
+ angle = np.array(CAMERA[camera_pose1]["angle"]) + np.array(CAMERA[camera_pose2]["angle"]) + np.array(CAMERA[camera_pose3]["angle"]) + np.array(CAMERA[camera_pose4]["angle"])
+ T = np.array(CAMERA[camera_pose1]["T"]) + np.array(CAMERA[camera_pose2]["T"]) + np.array(CAMERA[camera_pose3]["T"]) + np.array(CAMERA[camera_pose4]["T"])
+ RT = get_camera_motion(angle, T, speed, video_length)
+ return (RT,)
+
+class CameraJoinFromChaoJie:
+ # Copied from https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/blob/main/nodes.py
+ # Since ComfyUI-CameraCtrl-Wrapper requires a specific version of diffusers, which is not suitable for us.
+ # The code has been copied into the current repository.
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "camera_pose1":("CameraPose",),
+ "camera_pose2":("CameraPose",),
+ },
+ }
+
+ RETURN_TYPES = ("CameraPose",)
+ FUNCTION = "run"
+ CATEGORY = "CameraCtrl"
+
+ def run(self,camera_pose1,camera_pose2):
+ RT = combine_camera_motion(camera_pose1, camera_pose2)
+ return (RT,)
+
+class CameraTrajectoryFromChaoJie:
+ # Copied from https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/blob/main/nodes.py
+ # Since ComfyUI-CameraCtrl-Wrapper requires a specific version of diffusers, which is not suitable for us.
+ # The code has been copied into the current repository.
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "camera_pose":("CameraPose",),
+ "fx":("FLOAT",{"default":0.474812461, "min": 0, "max": 1, "step": 0.000000001}),
+ "fy":("FLOAT",{"default":0.844111024, "min": 0, "max": 1, "step": 0.000000001}),
+ "cx":("FLOAT",{"default":0.5, "min": 0, "max": 1, "step": 0.01}),
+ "cy":("FLOAT",{"default":0.5, "min": 0, "max": 1, "step": 0.01}),
+ },
+ }
+
+ RETURN_TYPES = ("STRING","INT",)
+ RETURN_NAMES = ("camera_trajectory","video_length",)
+ FUNCTION = "run"
+ CATEGORY = "CameraCtrl"
+
+ def run(self,camera_pose,fx,fy,cx,cy):
+ #print(camera_pose)
+ camera_pose_list=camera_pose.tolist()
+ trajs=[]
+ for cp in camera_pose_list:
+ traj=[fx,fy,cx,cy,0,0]
+ traj.extend(cp[0])
+ traj.extend(cp[1])
+ traj.extend(cp[2])
+ trajs.append(traj)
+ return (json.dumps(trajs),len(trajs),)
+
NODE_CLASS_MAPPINGS = {
"FunTextBox": FunTextBox,
"FunRiflex": FunRiflex,
@@ -74,6 +291,13 @@ NODE_CLASS_MAPPINGS = {
"VideoToCanny": VideoToCanny,
"VideoToDepth": VideoToDepth,
"VideoToOpenpose": VideoToPose,
+
+ "CreateTrajectoryBasedOnKJNodes": CreateTrajectoryBasedOnKJNodes,
+ "CameraBasicFromChaoJie": CameraBasicFromChaoJie,
+ "CameraTrajectoryFromChaoJie": CameraTrajectoryFromChaoJie,
+ "CameraJoinFromChaoJie": CameraJoinFromChaoJie,
+ "CameraCombineFromChaoJie": CameraCombineFromChaoJie,
+ "ImageMaximumNode": ImageMaximumNode,
}
@@ -101,4 +325,11 @@ NODE_DISPLAY_NAME_MAPPINGS = {
"VideoToCanny": "Video To Canny",
"VideoToDepth": "Video To Depth",
"VideoToOpenpose": "Video To Pose",
+
+ "CreateTrajectoryBasedOnKJNodes": "Create Trajectory Based On KJNodes",
+ "CameraBasicFromChaoJie": "Camera Basic From ChaoJie",
+ "CameraTrajectoryFromChaoJie": "Camera Trajectory From ChaoJie",
+ "CameraJoinFromChaoJie": "Camera Join From ChaoJie",
+ "CameraCombineFromChaoJie": "Camera Combine From ChaoJie",
+ "ImageMaximumNode": "Image Maximum Node",
}
\ No newline at end of file
diff --git a/comfyui/wan2_1/nodes.py b/comfyui/wan2_1/nodes.py
index 1e38923..3de29eb 100755
--- a/comfyui/wan2_1/nodes.py
+++ b/comfyui/wan2_1/nodes.py
@@ -344,6 +344,8 @@ class WanT2VSampler:
pipeline.transformer.enable_teacache(
coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
)
+ else:
+ pipeline.transformer.disable_teacache()
generator= torch.Generator(device).manual_seed(seed)
@@ -503,6 +505,8 @@ class WanI2VSampler:
pipeline.transformer.enable_teacache(
coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
)
+ else:
+ pipeline.transformer.disable_teacache()
generator= torch.Generator(device).manual_seed(seed)
diff --git a/comfyui/wan2_1_fun/nodes.py b/comfyui/wan2_1_fun/nodes.py
index 5c89551..8e56824 100755
--- a/comfyui/wan2_1_fun/nodes.py
+++ b/comfyui/wan2_1_fun/nodes.py
@@ -25,10 +25,11 @@ from ...videox_fun.ui.controller import all_cheduler_dict
from ...videox_fun.utils.fp8_optimization import (
convert_model_weight_to_float8, convert_weight_dtype_wrapper, replace_parameters_by_name)
from ...videox_fun.utils.lora_utils import merge_lora, unmerge_lora
-from ...videox_fun.utils.utils import (get_image_to_video_latent, filter_kwargs,
+from ...videox_fun.utils.utils import (get_image_to_video_latent, filter_kwargs, get_image_latent,
get_video_to_video_latent,
save_videos_grid)
from ...videox_fun.models.cache_utils import get_teacache_coefficients
+from ...videox_fun.data.dataset_image_video import process_pose_params
from ..comfyui_utils import eas_cache_dir, script_directory, to_pil
# Used in lora cache
@@ -46,7 +47,13 @@ class LoadWanFunModel:
'Wan2.1-Fun-1.3B-InP',
'Wan2.1-Fun-14B-InP',
'Wan2.1-Fun-1.3B-Control',
- 'Wan2.1-Fun-14B-Control'
+ 'Wan2.1-Fun-14B-Control',
+ 'Wan2.1-Fun-V1.1-1.3B-InP',
+ 'Wan2.1-Fun-V1.1-14B-InP',
+ 'Wan2.1-Fun-V1.1-1.3B-Control',
+ 'Wan2.1-Fun-V1.1-14B-Control',
+ 'Wan2.1-Fun-V1.1-1.3B-Control-Camera',
+ 'Wan2.1-Fun-V1.1-14B-Control-Camera',
],
{
"default": 'Wan2.1-Fun-1.3B-InP',
@@ -349,6 +356,8 @@ class WanFunT2VSampler:
pipeline.transformer.enable_teacache(
coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
)
+ else:
+ pipeline.transformer.disable_teacache()
generator= torch.Generator(device).manual_seed(seed)
@@ -526,6 +535,8 @@ class WanFunInpaintSampler:
pipeline.transformer.enable_teacache(
coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
)
+ else:
+ pipeline.transformer.disable_teacache()
generator= torch.Generator(device).manual_seed(seed)
@@ -654,7 +665,9 @@ class WanFunV2VSampler:
"optional": {
"validation_video": ("IMAGE",),
"control_video": ("IMAGE",),
+ "start_image": ("IMAGE",),
"ref_image": ("IMAGE",),
+ "camera_conditions": ("STRING", {"forceInput": True}),
"riflex_k": ("RIFLEXT_ARGS",),
},
}
@@ -664,7 +677,7 @@ class WanFunV2VSampler:
FUNCTION = "process"
CATEGORY = "CogVideoXFUNWrapper"
- def process(self, funmodels, prompt, negative_prompt, video_length, base_resolution, seed, steps, cfg, denoise_strength, scheduler, teacache_threshold, enable_teacache, num_skip_start_steps, teacache_offload, validation_video=None, control_video=None, ref_image=None, riflex_k=0):
+ def process(self, funmodels, prompt, negative_prompt, video_length, base_resolution, seed, steps, cfg, denoise_strength, scheduler, teacache_threshold, enable_teacache, num_skip_start_steps, teacache_offload, validation_video=None, control_video=None, start_image=None, ref_image=None, camera_conditions=None, riflex_k=0):
global transformer_cpu_cache
global lora_path_before
@@ -683,7 +696,7 @@ class WanFunV2VSampler:
# Count most suitable height and width
aspect_ratio_sample_size = {key : [x / 512 * base_resolution for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
- if model_type == "Inpaint":
+ if model_type == "Inpaint":
if type(validation_video) is str:
original_width, original_height = Image.fromarray(cv2.VideoCapture(validation_video).read()[1]).size
else:
@@ -701,6 +714,10 @@ class WanFunV2VSampler:
if ref_image is not None:
ref_image = [to_pil(_ref_image) for _ref_image in ref_image]
original_width, original_height = ref_image[0].size if type(ref_image) is list else Image.open(ref_image).size
+
+ if start_image is not None:
+ start_image = [to_pil(_start_image) for _start_image in start_image]
+ original_width, original_height = start_image[0].size if type(start_image) is list else Image.open(start_image).size
closest_size, closest_ratio = get_closest_ratio(original_height, original_width, ratios=aspect_ratio_sample_size)
height, width = [int(x / 16) * 16 for x in closest_size]
@@ -713,6 +730,8 @@ class WanFunV2VSampler:
pipeline.transformer.enable_teacache(
coefficients, steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
)
+ else:
+ pipeline.transformer.disable_teacache()
generator= torch.Generator(device).manual_seed(seed)
@@ -726,7 +745,29 @@ class WanFunV2VSampler:
if model_type == "Inpaint":
input_video, input_video_mask, ref_image, clip_image = get_video_to_video_latent(validation_video, video_length=video_length, sample_size=(height, width), fps=16, ref_image=ref_image[0] if ref_image is not None else ref_image)
else:
- input_video, input_video_mask, ref_image, clip_image = get_video_to_video_latent(control_video, video_length=video_length, sample_size=(height, width), fps=16, ref_image=ref_image[0] if ref_image is not None else ref_image)
+ if ref_image is not None:
+ clip_image = ref_image[0].convert("RGB")
+ elif start_image is not None:
+ clip_image = start_image[0].convert("RGB")
+ else:
+ clip_image = None
+
+ if ref_image is not None:
+ ref_image = get_image_latent(ref_image[0] if ref_image is not None else ref_image, sample_size=(height, width))
+
+ if start_image is not None:
+ start_image = get_image_latent(start_image[0] if start_image is not None else start_image, sample_size=(height, width))
+
+ if camera_conditions is not None and len(camera_conditions) > 0:
+ poses = json.loads(camera_conditions)
+ cam_params = np.array([[float(x) for x in pose] for pose in poses])
+ cam_params = np.concatenate([np.zeros_like(cam_params[:, :1]), cam_params], 1)
+ control_camera_video = process_pose_params(cam_params, width=width, height=height)
+ control_camera_video = control_camera_video[:video_length].permute([3, 0, 1, 2]).unsqueeze(0)
+ input_video, input_video_mask = None, None
+ else:
+ control_camera_video = None
+ input_video, input_video_mask, _, _ = get_video_to_video_latent(control_video, video_length=video_length, sample_size=(height, width), fps=16, ref_image=None)
# Apply lora
if funmodels.get("lora_cache", False):
@@ -785,8 +826,10 @@ class WanFunV2VSampler:
num_inference_steps = steps,
ref_image = ref_image,
+ start_image = start_image,
clip_image = clip_image,
control_video = input_video,
+ control_camera_video = control_camera_video,
comfyui_progressbar = True,
).videos
videos = rearrange(sample, "b c t h w -> (b t) h w c")
diff --git a/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_control_camera.json b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_control_camera.json
new file mode 100644
index 0000000..ef3aff3
--- /dev/null
+++ b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_control_camera.json
@@ -0,0 +1,665 @@
+{
+ "last_node_id": 132,
+ "last_link_id": 292,
+ "nodes": [
+ {
+ "id": 107,
+ "type": "Note",
+ "pos": {
+ "0": 4,
+ "1": 634
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 108,
+ "type": "Note",
+ "pos": {
+ "0": -110,
+ "1": 842
+ },
+ "size": {
+ "0": 326.1556091308594,
+ "1": 145.20904541015625
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 112,
+ "type": "Note",
+ "pos": {
+ "0": -203,
+ "1": 252
+ },
+ "size": {
+ "0": 427.074951171875,
+ "1": 143.9142608642578
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Due to the large size of models from EasyAnimateV5 and above, when using the 12B model, if your graphics card has 24GB or less of VRAM, please set GPU_memory_mode to model_cpu_offload_and_qfloat8. This will load the model in float8 to reduce VRAM consumption, otherwise you may receive an out-of-memory error. \n(由于EasyAnimateV5以上的模型较大,当使用12B模型时,如果使用的显卡显存为24G及以下,请将GPU_memory_mode设置为model_cpu_offload_and_qfloat8,使得模型加载在float8上减少显存消耗,否则会提示显存不足。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 122,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 238,
+ "1": 805
+ },
+ "size": {
+ "0": 400,
+ "1": 200
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 289
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 129,
+ "type": "CameraBasicFromChaoJie",
+ "pos": {
+ "0": 805.2059326171875,
+ "1": 1012.381103515625
+ },
+ "size": {
+ "0": 315,
+ "1": 106
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "CameraPose",
+ "type": "CameraPose",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CameraBasicFromChaoJie"
+ },
+ "widgets_values": [
+ "Static",
+ 1,
+ 16
+ ]
+ },
+ {
+ "id": 130,
+ "type": "CameraTrajectoryFromChaoJie",
+ "pos": {
+ "0": 1170.206298828125,
+ "1": 763.3814697265625
+ },
+ "size": {
+ "0": 367.79998779296875,
+ "1": 150
+ },
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "camera_pose",
+ "type": "CameraPose",
+ "link": 285
+ }
+ ],
+ "outputs": [
+ {
+ "name": "camera_trajectory",
+ "type": "STRING",
+ "links": [
+ 292
+ ],
+ "slot_index": 0
+ },
+ {
+ "name": "video_length",
+ "type": "INT",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CameraTrajectoryFromChaoJie"
+ },
+ "widgets_values": [
+ 0.532139961,
+ 0.946026558,
+ 0.5,
+ 0.5
+ ]
+ },
+ {
+ "id": 106,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1408,
+ "1": 68
+ },
+ "size": [
+ 390,
+ 537.4615384615385
+ ],
+ "flags": {},
+ "order": 12,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 291,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00061.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 121,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 235,
+ "1": 539
+ },
+ "size": {
+ "0": 400,
+ "1": 200
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 288
+ ]
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "Fireworks light up the evening sky over a sprawling cityscape with gothic-style buildings featuring pointed towers and clock faces. The city is lit by both artificial lights from the buildings and the colorful bursts of the fireworks. The scene is viewed from an elevated angle, showcasing a vibrant urban environment set against a backdrop of a dramatic, partially cloudy sky at dusk."
+ ]
+ },
+ {
+ "id": 100,
+ "type": "LoadImage",
+ "pos": {
+ "0": 237.59738159179688,
+ "1": 1164.597412109375
+ },
+ "size": {
+ "0": 378.07147216796875,
+ "1": 314
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 290
+ ],
+ "slot_index": 0,
+ "shape": 3,
+ "label": "图像"
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null,
+ "shape": 3,
+ "label": "遮罩"
+ }
+ ],
+ "title": "Start Image(图片到视频的开始图片)",
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "5.png",
+ "image"
+ ]
+ },
+ {
+ "id": 131,
+ "type": "CameraCombineFromChaoJie",
+ "pos": {
+ "0": 814.2059326171875,
+ "1": 763.3814697265625
+ },
+ "size": {
+ "0": 315,
+ "1": 178
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "CameraPose",
+ "type": "CameraPose",
+ "links": [
+ 285
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CameraCombineFromChaoJie"
+ },
+ "widgets_values": [
+ "Pan Right",
+ "Pan Up",
+ "Static",
+ "Static",
+ 1,
+ 81
+ ]
+ },
+ {
+ "id": 110,
+ "type": "Note",
+ "pos": {
+ "0": 1158.206298828125,
+ "1": 970.381103515625
+ },
+ "size": {
+ "0": 608.1410522460938,
+ "1": 188.2682342529297
+ },
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "CameraCombine is used to combine multiple camera movements, while CameraBasic produces a single camera movement. The nodes come from https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/. Since ComfyUI-CameraCtrl-Wrapper requires a specific version of diffusers, the code has been copied into the current repository.\n(CameraCombine用于组合多个镜头运动,CameraBasic产出单个镜头运动;节点来自于https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper/,由于ComfyUI-CameraCtrl-Wrapper有具体diffusers版本要求,故复制代码到当前库中。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 132,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 899,
+ "1": 68
+ },
+ "size": {
+ "0": 428.4000244140625,
+ "1": 486
+ },
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 287
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 288
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 289
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": 290,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": 292,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 291
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ ""
+ ]
+ },
+ {
+ "id": 123,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 281,
+ "1": 251
+ },
+ "size": {
+ "0": 315,
+ "1": 154
+ },
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 287
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control-Camera",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 285,
+ 131,
+ 0,
+ 130,
+ 0,
+ "CameraPose"
+ ],
+ [
+ 287,
+ 123,
+ 0,
+ 132,
+ 0,
+ "FunModels"
+ ],
+ [
+ 288,
+ 121,
+ 0,
+ 132,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 289,
+ 122,
+ 0,
+ 132,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 290,
+ 100,
+ 0,
+ 132,
+ 5,
+ "IMAGE"
+ ],
+ [
+ 291,
+ 132,
+ 0,
+ 106,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 292,
+ 130,
+ 0,
+ 132,
+ 8,
+ "STRING"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Generate Control Video",
+ "bounding": [
+ 773,
+ 666,
+ 1025,
+ 531
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "First Image",
+ "bounding": [
+ 191,
+ 1068,
+ 475,
+ 456
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 191,
+ 456,
+ 475,
+ 587
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load EasyAnimate",
+ "bounding": [
+ 189,
+ 160,
+ 475,
+ 269
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917358,
+ "offset": [
+ 28.17192681115923,
+ -3.293207324975433
+ ]
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "a7fa7028d52498f13e983eba012a81ebcae24977",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "comfy-core": "v0.2.7-3-g8afb97c"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_control_trajectory.json b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_control_trajectory.json
index 00d856e..44714c0 100644
--- a/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_control_trajectory.json
+++ b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_control_trajectory.json
@@ -1,6 +1,6 @@
{
- "last_node_id": 125,
- "last_link_id": 280,
+ "last_node_id": 126,
+ "last_link_id": 287,
"nodes": [
{
"id": 107,
@@ -97,7 +97,7 @@
"name": "IMAGE",
"type": "IMAGE",
"links": [
- 277
+ 285
],
"slot_index": 0,
"shape": 3,
@@ -217,7 +217,7 @@
"name": "prompt",
"type": "STRING_PROMPT",
"links": [
- 279
+ 282
]
}
],
@@ -247,7 +247,7 @@
{
"name": "video_1",
"type": "IMAGE",
- "link": 274
+ "link": 287
},
{
"name": "video_2",
@@ -305,7 +305,7 @@
"links": [
237,
262,
- 276
+ 284
],
"slot_index": 0
}
@@ -337,7 +337,7 @@
"name": "prompt",
"type": "STRING_PROMPT",
"links": [
- 278
+ 283
],
"slot_index": 0
}
@@ -350,164 +350,6 @@
"色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
]
},
- {
- "id": 106,
- "type": "VHS_VideoCombine",
- "pos": {
- "0": 1400,
- "1": 132
- },
- "size": [
- 390,
- 310
- ],
- "flags": {},
- "order": 14,
- "mode": 0,
- "inputs": [
- {
- "name": "images",
- "type": "IMAGE",
- "link": 273,
- "slot_index": 0,
- "label": "图像",
- "shape": 7
- },
- {
- "name": "audio",
- "type": "AUDIO",
- "link": null,
- "label": "音频",
- "shape": 7
- },
- {
- "name": "meta_batch",
- "type": "VHS_BatchManager",
- "link": null,
- "label": "批次管理",
- "shape": 7
- },
- {
- "name": "vae",
- "type": "VAE",
- "link": null,
- "shape": 7
- }
- ],
- "outputs": [
- {
- "name": "Filenames",
- "type": "VHS_FILENAMES",
- "links": null,
- "slot_index": 0,
- "shape": 3,
- "label": "文件名"
- }
- ],
- "properties": {
- "Node name for S&R": "VHS_VideoCombine"
- },
- "widgets_values": {
- "frame_rate": 16,
- "loop_count": 0,
- "filename_prefix": "Fun",
- "format": "video/h264-mp4",
- "pix_fmt": "yuv420p",
- "crf": 22,
- "save_metadata": true,
- "pingpong": false,
- "save_output": true,
- "videopreview": {
- "hidden": false,
- "paused": false,
- "params": {
- "filename": "EasyAnimate_00105.mp4",
- "subfolder": "",
- "type": "output",
- "format": "video/h264-mp4",
- "frame_rate": 8
- }
- }
- }
- },
- {
- "id": 125,
- "type": "WanFunV2VSampler",
- "pos": {
- "0": 907,
- "1": 129
- },
- "size": {
- "0": 428.4000244140625,
- "1": 422
- },
- "flags": {},
- "order": 13,
- "mode": 0,
- "inputs": [
- {
- "name": "funmodels",
- "type": "FunModels",
- "link": 280
- },
- {
- "name": "prompt",
- "type": "STRING_PROMPT",
- "link": 279
- },
- {
- "name": "negative_prompt",
- "type": "STRING_PROMPT",
- "link": 278
- },
- {
- "name": "validation_video",
- "type": "IMAGE",
- "link": null,
- "shape": 7
- },
- {
- "name": "control_video",
- "type": "IMAGE",
- "link": 276,
- "shape": 7
- },
- {
- "name": "ref_image",
- "type": "IMAGE",
- "link": 277,
- "shape": 7
- }
- ],
- "outputs": [
- {
- "name": "images",
- "type": "IMAGE",
- "links": [
- 273,
- 274
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "WanFunV2VSampler"
- },
- "widgets_values": [
- 81,
- 640,
- 528242892655931,
- "randomize",
- 50,
- 6,
- 1,
- "Flow",
- 0.1,
- true,
- 5,
- true
- ]
- },
{
"id": 97,
"type": "SplineEditor",
@@ -816,6 +658,185 @@
}
}
},
+ {
+ "id": 126,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 902,
+ "1": 60
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 13,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 281
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 282
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 283
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 284,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": 285,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 286,
+ 287
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ ""
+ ]
+ },
+ {
+ "id": 106,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1390,
+ "1": 61
+ },
+ "size": [
+ 390,
+ 310
+ ],
+ "flags": {},
+ "order": 14,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 286,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "EasyAnimate_00105.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ },
{
"id": 123,
"type": "LoadWanFunModel",
@@ -836,7 +857,7 @@
"name": "funmodels",
"type": "FunModels",
"links": [
- 280
+ 281
],
"slot_index": 0
}
@@ -845,7 +866,7 @@
"Node name for S&R": "LoadWanFunModel"
},
"widgets_values": [
- "Wan2.1-Fun-1.3B-Control",
+ "Wan2.1-Fun-V1.1-1.3B-Control",
"Control",
"model_cpu_offload",
"wan2.1/wan_civitai.yaml",
@@ -911,60 +932,60 @@
"STRING"
],
[
- 273,
- 125,
+ 281,
+ 123,
+ 0,
+ 126,
+ 0,
+ "FunModels"
+ ],
+ [
+ 282,
+ 121,
+ 0,
+ 126,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 283,
+ 122,
+ 0,
+ 126,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 284,
+ 95,
+ 0,
+ 126,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 285,
+ 100,
+ 0,
+ 126,
+ 5,
+ "IMAGE"
+ ],
+ [
+ 286,
+ 126,
0,
106,
0,
"IMAGE"
],
[
- 274,
- 125,
+ 287,
+ 126,
0,
114,
0,
"IMAGE"
- ],
- [
- 276,
- 95,
- 0,
- 125,
- 4,
- "IMAGE"
- ],
- [
- 277,
- 100,
- 0,
- 125,
- 5,
- "IMAGE"
- ],
- [
- 278,
- 122,
- 0,
- 125,
- 2,
- "STRING_PROMPT"
- ],
- [
- 279,
- 121,
- 0,
- 125,
- 1,
- "STRING_PROMPT"
- ],
- [
- 280,
- 123,
- 0,
- 125,
- 0,
- "FunModels"
]
],
"groups": [
@@ -1020,17 +1041,16 @@
"config": {},
"extra": {
"ds": {
- "scale": 0.6209213230591555,
+ "scale": 0.6830134553650709,
"offset": [
- -272.6643790445752,
- -176.47199796461615
+ 198.78755142053404,
+ 143.5866129875247
]
},
"node_versions": {
"comfy-core": "v0.2.7-3-g8afb97c",
"ComfyUI-KJNodes": "4c5c26a2c91de356212419ac8bc7fcf9869527e9",
- "CogVideoX-Fun": "e054344e39c5030c23b0146ed4a1293bff2505ed",
- "EasyAnimate": "c2a70d17daa1549a22129d0cd0e02053ecccd75c",
+ "CogVideoX-Fun": "717f0629175ad192927dc51ec95c4376816a4212",
"ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
}
},
diff --git a/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control.json b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control.json
index 722b3f4..ffe0549 100644
--- a/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control.json
+++ b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control.json
@@ -1,6 +1,6 @@
{
- "last_node_id": 96,
- "last_link_id": 60,
+ "last_node_id": 97,
+ "last_link_id": 65,
"nodes": [
{
"id": 78,
@@ -135,7 +135,7 @@
"name": "IMAGE",
"type": "IMAGE",
"links": [
- 60
+ 64
],
"slot_index": 0,
"shape": 3
@@ -188,62 +188,26 @@
}
},
{
- "id": 95,
- "type": "LoadWanFunModel",
+ "id": 92,
+ "type": "FunTextBox",
"pos": {
- "0": 275,
- "1": -309
+ "0": 254,
+ "1": -46
},
"size": {
- "0": 435.2322082519531,
- "1": 154
+ "0": 380.845703125,
+ "1": 157.68350219726562
},
"flags": {},
"order": 5,
"mode": 0,
"inputs": [],
- "outputs": [
- {
- "name": "funmodels",
- "type": "FunModels",
- "links": [
- 59
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "LoadWanFunModel"
- },
- "widgets_values": [
- "Wan2.1-Fun-1.3B-Control",
- "Control",
- "model_cpu_offload",
- "wan2.1/wan_civitai.yaml",
- "bf16"
- ]
- },
- {
- "id": 92,
- "type": "FunTextBox",
- "pos": {
- "0": 254,
- "1": -46
- },
- "size": [
- 380.84570316445,
- 157.68350713493612
- ],
- "flags": {},
- "order": 6,
- "mode": 0,
- "inputs": [],
"outputs": [
{
"name": "prompt",
"type": "STRING_PROMPT",
"links": [
- 57
+ 62
],
"slot_index": 0
}
@@ -263,12 +227,12 @@
"0": 258,
"1": 178
},
- "size": [
- 368.5529492582,
- 159.40758916618609
- ],
+ "size": {
+ "0": 368.5529479980469,
+ "1": 159.4075927734375
+ },
"flags": {},
- "order": 7,
+ "order": 6,
"mode": 0,
"inputs": [],
"outputs": [
@@ -276,7 +240,7 @@
"name": "prompt",
"type": "STRING_PROMPT",
"links": [
- 58
+ 63
],
"slot_index": 0
}
@@ -306,7 +270,7 @@
{
"name": "images",
"type": "IMAGE",
- "link": 54,
+ "link": 65,
"slot_index": 0,
"label": "图像",
"shape": 7
@@ -369,16 +333,16 @@
}
},
{
- "id": 91,
+ "id": 97,
"type": "WanFunV2VSampler",
"pos": {
"0": 792,
"1": 11
},
- "size": {
- "0": 428.4000244140625,
- "1": 422
- },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
"flags": {},
"order": 8,
"mode": 0,
@@ -386,17 +350,17 @@
{
"name": "funmodels",
"type": "FunModels",
- "link": 59
+ "link": 61
},
{
"name": "prompt",
"type": "STRING_PROMPT",
- "link": 57
+ "link": 62
},
{
"name": "negative_prompt",
"type": "STRING_PROMPT",
- "link": 58
+ "link": 63
},
{
"name": "validation_video",
@@ -407,7 +371,13 @@
{
"name": "control_video",
"type": "IMAGE",
- "link": 60,
+ "link": 64,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
"shape": 7
},
{
@@ -415,6 +385,21 @@
"type": "IMAGE",
"link": null,
"shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
}
],
"outputs": [
@@ -422,7 +407,7 @@
"name": "images",
"type": "IMAGE",
"links": [
- 54
+ 65
]
}
],
@@ -430,73 +415,110 @@
"Node name for S&R": "WanFunV2VSampler"
},
"widgets_values": [
- 49,
+ 81,
640,
43,
"fixed",
50,
6,
- 1,
+ 1.0,
"Flow",
0.1,
true,
5,
- true
+ true,
+ ""
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 61
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
]
}
],
"links": [
[
- 54,
- 91,
- 0,
- 17,
- 0,
- "IMAGE"
- ],
- [
- 57,
- 92,
- 0,
- 91,
- 1,
- "STRING_PROMPT"
- ],
- [
- 58,
- 94,
- 0,
- 91,
- 2,
- "STRING_PROMPT"
- ],
- [
- 59,
+ 61,
95,
0,
- 91,
+ 97,
0,
"FunModels"
],
[
- 60,
+ 62,
+ 92,
+ 0,
+ 97,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 63,
+ 94,
+ 0,
+ 97,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 64,
85,
0,
- 91,
+ 97,
4,
"IMAGE"
+ ],
+ [
+ 65,
+ 97,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
]
],
"groups": [
{
- "title": "Upload Your Video",
+ "title": "Prompts",
"bounding": [
218,
- 385,
- 487,
- 789
+ -127,
+ 450,
+ 483
],
- "color": "#a1309b",
+ "color": "#3f789e",
"font_size": 24,
"flags": {}
},
@@ -513,14 +535,14 @@
"flags": {}
},
{
- "title": "Prompts",
+ "title": "Upload Your Video",
"bounding": [
218,
- -127,
- 450,
- 483
+ 385,
+ 487,
+ 789
],
- "color": "#3f789e",
+ "color": "#a1309b",
"font_size": 24,
"flags": {}
}
@@ -528,10 +550,10 @@
"config": {},
"extra": {
"ds": {
- "scale": 0.5644739300537773,
+ "scale": 0.6830134553650709,
"offset": [
- 565.8477434839879,
- 453.10373146272065
+ 249.86519634240904,
+ 438.3739973625246
]
},
"workspace_info": {
@@ -539,7 +561,7 @@
},
"node_versions": {
"ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
- "CogVideoX-Fun": "e054344e39c5030c23b0146ed4a1293bff2505ed"
+ "CogVideoX-Fun": "717f0629175ad192927dc51ec95c4376816a4212"
}
},
"version": 0.4
diff --git a/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_canny.json b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_canny.json
index 6a3bebb..9a28b03 100644
--- a/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_canny.json
+++ b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_canny.json
@@ -1,6 +1,6 @@
{
- "last_node_id": 99,
- "last_link_id": 66,
+ "last_node_id": 100,
+ "last_link_id": 71,
"nodes": [
{
"id": 78,
@@ -102,42 +102,6 @@
"color": "#432",
"bgcolor": "#653"
},
- {
- "id": 95,
- "type": "LoadWanFunModel",
- "pos": {
- "0": 275,
- "1": -309
- },
- "size": {
- "0": 435.2322082519531,
- "1": 154
- },
- "flags": {},
- "order": 4,
- "mode": 0,
- "inputs": [],
- "outputs": [
- {
- "name": "funmodels",
- "type": "FunModels",
- "links": [
- 59
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "LoadWanFunModel"
- },
- "widgets_values": [
- "Wan2.1-Fun-1.3B-Control",
- "Control",
- "model_cpu_offload",
- "wan2.1/wan_civitai.yaml",
- "bf16"
- ]
- },
{
"id": 92,
"type": "FunTextBox",
@@ -150,7 +114,7 @@
"1": 157.68350219726562
},
"flags": {},
- "order": 5,
+ "order": 4,
"mode": 0,
"inputs": [],
"outputs": [
@@ -158,7 +122,7 @@
"name": "prompt",
"type": "STRING_PROMPT",
"links": [
- 57
+ 68
],
"slot_index": 0
}
@@ -183,7 +147,7 @@
"1": 159.4075927734375
},
"flags": {},
- "order": 6,
+ "order": 5,
"mode": 0,
"inputs": [],
"outputs": [
@@ -191,7 +155,7 @@
"name": "prompt",
"type": "STRING_PROMPT",
"links": [
- 58
+ 69
],
"slot_index": 0
}
@@ -203,163 +167,6 @@
"色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
]
},
- {
- "id": 17,
- "type": "VHS_VideoCombine",
- "pos": {
- "0": 1488,
- "1": 8
- },
- "size": [
- 390.9534912109375,
- 966.9860514322917
- ],
- "flags": {},
- "order": 11,
- "mode": 0,
- "inputs": [
- {
- "name": "images",
- "type": "IMAGE",
- "link": 54,
- "slot_index": 0,
- "label": "图像",
- "shape": 7
- },
- {
- "name": "audio",
- "type": "AUDIO",
- "link": null,
- "label": "音频",
- "shape": 7
- },
- {
- "name": "meta_batch",
- "type": "VHS_BatchManager",
- "link": null,
- "label": "批次管理",
- "shape": 7
- },
- {
- "name": "vae",
- "type": "VAE",
- "link": null,
- "shape": 7
- }
- ],
- "outputs": [
- {
- "name": "Filenames",
- "type": "VHS_FILENAMES",
- "links": null,
- "slot_index": 0,
- "shape": 3,
- "label": "文件名"
- }
- ],
- "properties": {
- "Node name for S&R": "VHS_VideoCombine"
- },
- "widgets_values": {
- "frame_rate": 16,
- "loop_count": 0,
- "filename_prefix": "Fun",
- "format": "video/h264-mp4",
- "pix_fmt": "yuv420p",
- "crf": 22,
- "save_metadata": true,
- "pingpong": false,
- "save_output": true,
- "videopreview": {
- "hidden": false,
- "paused": false,
- "params": {
- "filename": "Fun_00004.mp4",
- "subfolder": "",
- "type": "output",
- "format": "video/h264-mp4",
- "frame_rate": 16
- }
- }
- }
- },
- {
- "id": 91,
- "type": "WanFunV2VSampler",
- "pos": {
- "0": 996,
- "1": 9
- },
- "size": {
- "0": 428.4000244140625,
- "1": 422
- },
- "flags": {},
- "order": 9,
- "mode": 0,
- "inputs": [
- {
- "name": "funmodels",
- "type": "FunModels",
- "link": 59
- },
- {
- "name": "prompt",
- "type": "STRING_PROMPT",
- "link": 57
- },
- {
- "name": "negative_prompt",
- "type": "STRING_PROMPT",
- "link": 58
- },
- {
- "name": "validation_video",
- "type": "IMAGE",
- "link": null,
- "shape": 7
- },
- {
- "name": "control_video",
- "type": "IMAGE",
- "link": 62,
- "shape": 7
- },
- {
- "name": "ref_image",
- "type": "IMAGE",
- "link": null,
- "shape": 7
- }
- ],
- "outputs": [
- {
- "name": "images",
- "type": "IMAGE",
- "links": [
- 54
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "WanFunV2VSampler"
- },
- "widgets_values": [
- 49,
- 640,
- 43,
- "fixed",
- 50,
- 6,
- 1,
- "Flow",
- 0.1,
- true,
- 5,
- true
- ]
- },
{
"id": 85,
"type": "VHS_LoadVideo",
@@ -372,7 +179,7 @@
262
],
"flags": {},
- "order": 7,
+ "order": 6,
"mode": 0,
"inputs": [
{
@@ -471,8 +278,8 @@
"name": "images",
"type": "IMAGE",
"links": [
- 62,
- 65
+ 65,
+ 70
],
"slot_index": 0
}
@@ -493,12 +300,12 @@
"0": 1094,
"1": 559
},
- "size": [
- 315,
- 851.4834437086093
- ],
+ "size": {
+ "0": 315,
+ "1": 310
+ },
"flags": {},
- "order": 10,
+ "order": 9,
"mode": 0,
"inputs": [
{
@@ -558,49 +365,223 @@
}
}
}
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1467,
+ "1": -158
+ },
+ "size": [
+ 390.9534912109375,
+ 966.9860514322917
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 71,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00004.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 100,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 973,
+ "1": -160
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 67
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 68
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 69
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 70,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 71
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ ""
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 67
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
}
],
"links": [
- [
- 54,
- 91,
- 0,
- 17,
- 0,
- "IMAGE"
- ],
- [
- 57,
- 92,
- 0,
- 91,
- 1,
- "STRING_PROMPT"
- ],
- [
- 58,
- 94,
- 0,
- 91,
- 2,
- "STRING_PROMPT"
- ],
- [
- 59,
- 95,
- 0,
- 91,
- 0,
- "FunModels"
- ],
- [
- 62,
- 97,
- 0,
- 91,
- 4,
- "IMAGE"
- ],
[
65,
97,
@@ -616,6 +597,46 @@
97,
0,
"IMAGE"
+ ],
+ [
+ 67,
+ 95,
+ 0,
+ 100,
+ 0,
+ "FunModels"
+ ],
+ [
+ 68,
+ 92,
+ 0,
+ 100,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 69,
+ 94,
+ 0,
+ 100,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 70,
+ 97,
+ 0,
+ 100,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 71,
+ 100,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
]
],
"groups": [
@@ -659,17 +680,17 @@
"config": {},
"extra": {
"ds": {
- "scale": 0.7513148009015777,
+ "scale": 0.6830134553650709,
"offset": [
- -93.39355666991875,
- 76.6941257863825
+ 249.86519634240904,
+ 438.3739973625246
]
},
"workspace_info": {
"id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
},
"node_versions": {
- "CogVideoX-Fun": "235039911acf7b9d614b797dafe2230318d39a80",
+ "CogVideoX-Fun": "717f0629175ad192927dc51ec95c4376816a4212",
"ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
}
},
diff --git a/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_depth.json b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_depth.json
index d276f05..f697d97 100644
--- a/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_depth.json
+++ b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_depth.json
@@ -1,6 +1,6 @@
{
- "last_node_id": 100,
- "last_link_id": 70,
+ "last_node_id": 101,
+ "last_link_id": 75,
"nodes": [
{
"id": 78,
@@ -102,42 +102,6 @@
"color": "#432",
"bgcolor": "#653"
},
- {
- "id": 95,
- "type": "LoadWanFunModel",
- "pos": {
- "0": 275,
- "1": -309
- },
- "size": {
- "0": 435.2322082519531,
- "1": 154
- },
- "flags": {},
- "order": 4,
- "mode": 0,
- "inputs": [],
- "outputs": [
- {
- "name": "funmodels",
- "type": "FunModels",
- "links": [
- 59
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "LoadWanFunModel"
- },
- "widgets_values": [
- "Wan2.1-Fun-1.3B-Control",
- "Control",
- "model_cpu_offload",
- "wan2.1/wan_civitai.yaml",
- "bf16"
- ]
- },
{
"id": 92,
"type": "FunTextBox",
@@ -150,7 +114,7 @@
"1": 157.68350219726562
},
"flags": {},
- "order": 5,
+ "order": 4,
"mode": 0,
"inputs": [],
"outputs": [
@@ -158,7 +122,7 @@
"name": "prompt",
"type": "STRING_PROMPT",
"links": [
- 57
+ 72
],
"slot_index": 0
}
@@ -183,7 +147,7 @@
"1": 159.4075927734375
},
"flags": {},
- "order": 6,
+ "order": 5,
"mode": 0,
"inputs": [],
"outputs": [
@@ -191,7 +155,7 @@
"name": "prompt",
"type": "STRING_PROMPT",
"links": [
- 58
+ 73
],
"slot_index": 0
}
@@ -203,86 +167,6 @@
"色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
]
},
- {
- "id": 17,
- "type": "VHS_VideoCombine",
- "pos": {
- "0": 1488,
- "1": 8
- },
- "size": [
- 390.9534912109375,
- 966.9860514322917
- ],
- "flags": {},
- "order": 11,
- "mode": 0,
- "inputs": [
- {
- "name": "images",
- "type": "IMAGE",
- "link": 54,
- "slot_index": 0,
- "label": "图像",
- "shape": 7
- },
- {
- "name": "audio",
- "type": "AUDIO",
- "link": null,
- "label": "音频",
- "shape": 7
- },
- {
- "name": "meta_batch",
- "type": "VHS_BatchManager",
- "link": null,
- "label": "批次管理",
- "shape": 7
- },
- {
- "name": "vae",
- "type": "VAE",
- "link": null,
- "shape": 7
- }
- ],
- "outputs": [
- {
- "name": "Filenames",
- "type": "VHS_FILENAMES",
- "links": null,
- "slot_index": 0,
- "shape": 3,
- "label": "文件名"
- }
- ],
- "properties": {
- "Node name for S&R": "VHS_VideoCombine"
- },
- "widgets_values": {
- "frame_rate": 16,
- "loop_count": 0,
- "filename_prefix": "Fun",
- "format": "video/h264-mp4",
- "pix_fmt": "yuv420p",
- "crf": 22,
- "save_metadata": true,
- "pingpong": false,
- "save_output": true,
- "videopreview": {
- "hidden": false,
- "paused": false,
- "params": {
- "filename": "Fun_00039.mp4",
- "subfolder": "",
- "type": "output",
- "format": "video/h264-mp4",
- "frame_rate": 16
- }
- }
- }
- },
{
"id": 85,
"type": "VHS_LoadVideo",
@@ -295,7 +179,7 @@
262
],
"flags": {},
- "order": 7,
+ "order": 6,
"mode": 0,
"inputs": [
{
@@ -395,7 +279,7 @@
"type": "IMAGE",
"links": [
68,
- 69
+ 74
],
"slot_index": 0
}
@@ -407,83 +291,6 @@
81
]
},
- {
- "id": 91,
- "type": "WanFunV2VSampler",
- "pos": {
- "0": 996,
- "1": 9
- },
- "size": {
- "0": 428.4000244140625,
- "1": 422
- },
- "flags": {},
- "order": 10,
- "mode": 0,
- "inputs": [
- {
- "name": "funmodels",
- "type": "FunModels",
- "link": 59
- },
- {
- "name": "prompt",
- "type": "STRING_PROMPT",
- "link": 57
- },
- {
- "name": "negative_prompt",
- "type": "STRING_PROMPT",
- "link": 58
- },
- {
- "name": "validation_video",
- "type": "IMAGE",
- "link": null,
- "shape": 7
- },
- {
- "name": "control_video",
- "type": "IMAGE",
- "link": 69,
- "shape": 7
- },
- {
- "name": "ref_image",
- "type": "IMAGE",
- "link": null,
- "shape": 7
- }
- ],
- "outputs": [
- {
- "name": "images",
- "type": "IMAGE",
- "links": [
- 54
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "WanFunV2VSampler"
- },
- "widgets_values": [
- 49,
- 640,
- 43,
- "fixed",
- 50,
- 6,
- 1,
- "Flow",
- 0.1,
- true,
- 5,
- true
- ]
- },
{
"id": 99,
"type": "VHS_VideoCombine",
@@ -491,10 +298,10 @@
"0": 996,
"1": 505
},
- "size": [
- 315,
- 851.197265625
- ],
+ "size": {
+ "0": 315,
+ "1": 310
+ },
"flags": {},
"order": 9,
"mode": 0,
@@ -556,41 +363,223 @@
}
}
}
+ },
+ {
+ "id": 101,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 989,
+ "1": -180
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 71
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 72
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 73
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 74,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 75
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ ""
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 71
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1459,
+ "1": -180
+ },
+ "size": [
+ 390.9534912109375,
+ 966.9860514322917
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 75,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00039.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
}
],
"links": [
- [
- 54,
- 91,
- 0,
- 17,
- 0,
- "IMAGE"
- ],
- [
- 57,
- 92,
- 0,
- 91,
- 1,
- "STRING_PROMPT"
- ],
- [
- 58,
- 94,
- 0,
- 91,
- 2,
- "STRING_PROMPT"
- ],
- [
- 59,
- 95,
- 0,
- 91,
- 0,
- "FunModels"
- ],
[
68,
100,
@@ -599,14 +588,6 @@
0,
"IMAGE"
],
- [
- 69,
- 100,
- 0,
- 91,
- 4,
- "IMAGE"
- ],
[
70,
85,
@@ -614,6 +595,46 @@
100,
0,
"IMAGE"
+ ],
+ [
+ 71,
+ 95,
+ 0,
+ 101,
+ 0,
+ "FunModels"
+ ],
+ [
+ 72,
+ 92,
+ 0,
+ 101,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 73,
+ 94,
+ 0,
+ 101,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 74,
+ 100,
+ 0,
+ 101,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 75,
+ 101,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
]
],
"groups": [
@@ -657,17 +678,17 @@
"config": {},
"extra": {
"ds": {
- "scale": 0.7513148009015777,
+ "scale": 0.6830134553650709,
"offset": [
- -93.39355666991875,
- 76.6941257863825
+ 249.86519634240904,
+ 438.3739973625246
]
},
"workspace_info": {
"id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
},
"node_versions": {
- "CogVideoX-Fun": "235039911acf7b9d614b797dafe2230318d39a80",
+ "CogVideoX-Fun": "717f0629175ad192927dc51ec95c4376816a4212",
"ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
}
},
diff --git a/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_depth_ref.json b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_depth_ref.json
new file mode 100644
index 0000000..46f4f7f
--- /dev/null
+++ b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_depth_ref.json
@@ -0,0 +1,742 @@
+{
+ "last_node_id": 104,
+ "last_link_id": 85,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": {
+ "0": -111.46612548828125,
+ "1": 460.2178955078125
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": {
+ "0": -99,
+ "1": 197
+ },
+ "size": {
+ "0": 326.1556091308594,
+ "1": 145.20904541015625
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": {
+ "0": -192,
+ "1": -293
+ },
+ "size": {
+ "0": 427.074951171875,
+ "1": 143.9142608642578
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 258,
+ "1": 178
+ },
+ "size": {
+ "0": 368.5529479980469,
+ "1": 159.4075927734375
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 82
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1488,
+ "1": 8
+ },
+ "size": [
+ 390.9534912109375,
+ 942.2558186848959
+ ],
+ "flags": {},
+ "order": 12,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 85,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00050.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 99,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1005,
+ "1": 554
+ },
+ "size": [
+ 315,
+ 849.46875
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 79,
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun-Preprocess-Video",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 19,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun-Preprocess-Video_00008.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 102,
+ "type": "LoadImage",
+ "pos": {
+ "0": 553,
+ "1": 598
+ },
+ "size": {
+ "0": 315,
+ "1": 314
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 84
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "9.png",
+ "image"
+ ]
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 254,
+ "1": -46
+ },
+ "size": {
+ "0": 380.845703125,
+ "1": 157.68350219726562
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 81
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "一位动漫风格的女孩。她有着紫色的短发,头上戴着一个黑色和金色相间的蝴蝶结。她的表情显得有些严肃或沉思,眼睛大而有神。女孩穿着一件白色衬衫,外面搭配了一件深蓝色的背心,背心上有一个粉色的蝴蝶结装饰。她的裙子是白色的,裙摆蓬松,整体造型非常可爱且精致。背景是一个简单的圆形图案,颜色为粉红色和灰色相间,给人一种柔和的感觉。整个画面色调柔和,人物形象生动鲜明。"
+ ]
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": {
+ "0": 207.79391479492188,
+ "1": 473.83123779296875
+ },
+ "size": [
+ 252.056640625,
+ 688.5451388888889
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 76
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "000007.mp4",
+ "force_rate": 16,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 16,
+ "filename": "000007.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 103,
+ "type": "VideoToDepth",
+ "pos": {
+ "0": 553,
+ "1": 472
+ },
+ "size": {
+ "0": 315,
+ "1": 58
+ },
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "input_video",
+ "type": "IMAGE",
+ "link": 76
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 79,
+ 83
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VideoToDepth"
+ },
+ "widgets_values": [
+ 81
+ ]
+ },
+ {
+ "id": 104,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 996,
+ "1": 9
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 80
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 81
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 82
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 83,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": 84,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 85
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 490544951141590,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ ""
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 80
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ }
+ ],
+ "links": [
+ [
+ 76,
+ 85,
+ 0,
+ 103,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 79,
+ 103,
+ 0,
+ 99,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 80,
+ 95,
+ 0,
+ 104,
+ 0,
+ "FunModels"
+ ],
+ [
+ 81,
+ 92,
+ 0,
+ 104,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 82,
+ 94,
+ 0,
+ 104,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 83,
+ 103,
+ 0,
+ 104,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 84,
+ 102,
+ 0,
+ 104,
+ 6,
+ "IMAGE"
+ ],
+ [
+ 85,
+ 104,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Upload Your Video And Reference Image",
+ "bounding": [
+ 91,
+ 383,
+ 859,
+ 841
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load EasyAnimate",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650709,
+ "offset": [
+ 246.99418774865902,
+ 428.7658411125245
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "a7fa7028d52498f13e983eba012a81ebcae24977",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "comfy-core": "v0.2.7-3-g8afb97c"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_pose.json b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_pose.json
index 4c20cb1..e5eb6fd 100644
--- a/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_pose.json
+++ b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_pose.json
@@ -1,6 +1,6 @@
{
- "last_node_id": 101,
- "last_link_id": 74,
+ "last_node_id": 102,
+ "last_link_id": 79,
"nodes": [
{
"id": 78,
@@ -102,42 +102,6 @@
"color": "#432",
"bgcolor": "#653"
},
- {
- "id": 95,
- "type": "LoadWanFunModel",
- "pos": {
- "0": 275,
- "1": -309
- },
- "size": {
- "0": 435.2322082519531,
- "1": 154
- },
- "flags": {},
- "order": 4,
- "mode": 0,
- "inputs": [],
- "outputs": [
- {
- "name": "funmodels",
- "type": "FunModels",
- "links": [
- 59
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "LoadWanFunModel"
- },
- "widgets_values": [
- "Wan2.1-Fun-1.3B-Control",
- "Control",
- "model_cpu_offload",
- "wan2.1/wan_civitai.yaml",
- "bf16"
- ]
- },
{
"id": 92,
"type": "FunTextBox",
@@ -150,7 +114,7 @@
"1": 157.68350219726562
},
"flags": {},
- "order": 5,
+ "order": 4,
"mode": 0,
"inputs": [],
"outputs": [
@@ -158,7 +122,7 @@
"name": "prompt",
"type": "STRING_PROMPT",
"links": [
- 57
+ 76
],
"slot_index": 0
}
@@ -183,7 +147,7 @@
"1": 159.4075927734375
},
"flags": {},
- "order": 6,
+ "order": 5,
"mode": 0,
"inputs": [],
"outputs": [
@@ -191,7 +155,7 @@
"name": "prompt",
"type": "STRING_PROMPT",
"links": [
- 58
+ 77
],
"slot_index": 0
}
@@ -203,86 +167,6 @@
"色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
]
},
- {
- "id": 17,
- "type": "VHS_VideoCombine",
- "pos": {
- "0": 1488,
- "1": 8
- },
- "size": [
- 390.9534912109375,
- 966.9860514322917
- ],
- "flags": {},
- "order": 11,
- "mode": 0,
- "inputs": [
- {
- "name": "images",
- "type": "IMAGE",
- "link": 54,
- "slot_index": 0,
- "label": "图像",
- "shape": 7
- },
- {
- "name": "audio",
- "type": "AUDIO",
- "link": null,
- "label": "音频",
- "shape": 7
- },
- {
- "name": "meta_batch",
- "type": "VHS_BatchManager",
- "link": null,
- "label": "批次管理",
- "shape": 7
- },
- {
- "name": "vae",
- "type": "VAE",
- "link": null,
- "shape": 7
- }
- ],
- "outputs": [
- {
- "name": "Filenames",
- "type": "VHS_FILENAMES",
- "links": null,
- "slot_index": 0,
- "shape": 3,
- "label": "文件名"
- }
- ],
- "properties": {
- "Node name for S&R": "VHS_VideoCombine"
- },
- "widgets_values": {
- "frame_rate": 16,
- "loop_count": 0,
- "filename_prefix": "Fun",
- "format": "video/h264-mp4",
- "pix_fmt": "yuv420p",
- "crf": 22,
- "save_metadata": true,
- "pingpong": false,
- "save_output": true,
- "videopreview": {
- "hidden": false,
- "paused": false,
- "params": {
- "filename": "Fun_00041.mp4",
- "subfolder": "",
- "type": "output",
- "format": "video/h264-mp4",
- "frame_rate": 16
- }
- }
- }
- },
{
"id": 85,
"type": "VHS_LoadVideo",
@@ -295,7 +179,7 @@
262
],
"flags": {},
- "order": 7,
+ "order": 6,
"mode": 0,
"inputs": [
{
@@ -368,89 +252,12 @@
}
}
},
- {
- "id": 91,
- "type": "WanFunV2VSampler",
- "pos": {
- "0": 996,
- "1": 9
- },
- "size": {
- "0": 428.4000244140625,
- "1": 422
- },
- "flags": {},
- "order": 10,
- "mode": 0,
- "inputs": [
- {
- "name": "funmodels",
- "type": "FunModels",
- "link": 59
- },
- {
- "name": "prompt",
- "type": "STRING_PROMPT",
- "link": 57
- },
- {
- "name": "negative_prompt",
- "type": "STRING_PROMPT",
- "link": 58
- },
- {
- "name": "validation_video",
- "type": "IMAGE",
- "link": null,
- "shape": 7
- },
- {
- "name": "control_video",
- "type": "IMAGE",
- "link": 74,
- "shape": 7
- },
- {
- "name": "ref_image",
- "type": "IMAGE",
- "link": null,
- "shape": 7
- }
- ],
- "outputs": [
- {
- "name": "images",
- "type": "IMAGE",
- "links": [
- 54
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "WanFunV2VSampler"
- },
- "widgets_values": [
- 49,
- 640,
- 43,
- "fixed",
- 50,
- 6,
- 1,
- "Flow",
- 0.1,
- true,
- 5,
- true
- ]
- },
{
"id": 101,
"type": "VideoToOpenpose",
"pos": {
- "0": 734,
- "1": 508
+ "0": 719,
+ "1": 542
},
"size": {
"0": 315,
@@ -472,7 +279,7 @@
"type": "IMAGE",
"links": [
73,
- 74
+ 78
],
"slot_index": 0
}
@@ -488,8 +295,8 @@
"id": 99,
"type": "VHS_VideoCombine",
"pos": {
- "0": 1098,
- "1": 505
+ "0": 1067,
+ "1": 540
},
"size": [
315,
@@ -556,41 +363,223 @@
}
}
}
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1432,
+ "1": -135
+ },
+ "size": [
+ 390.9534912109375,
+ 966.9860514322917
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 79,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00041.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 102,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 890,
+ "1": -136
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 75
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 76
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 77
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 78,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 79
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ ""
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 75
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
}
],
"links": [
- [
- 54,
- 91,
- 0,
- 17,
- 0,
- "IMAGE"
- ],
- [
- 57,
- 92,
- 0,
- 91,
- 1,
- "STRING_PROMPT"
- ],
- [
- 58,
- 94,
- 0,
- 91,
- 2,
- "STRING_PROMPT"
- ],
- [
- 59,
- 95,
- 0,
- 91,
- 0,
- "FunModels"
- ],
[
72,
85,
@@ -608,12 +597,44 @@
"IMAGE"
],
[
- 74,
+ 75,
+ 95,
+ 0,
+ 102,
+ 0,
+ "FunModels"
+ ],
+ [
+ 76,
+ 92,
+ 0,
+ 102,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 77,
+ 94,
+ 0,
+ 102,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 78,
101,
0,
- 91,
+ 102,
4,
"IMAGE"
+ ],
+ [
+ 79,
+ 102,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
]
],
"groups": [
@@ -657,17 +678,17 @@
"config": {},
"extra": {
"ds": {
- "scale": 0.7513148009015777,
+ "scale": 0.6830134553650709,
"offset": [
- -93.39355666991875,
- 76.6941257863825
+ 249.86519634240904,
+ 438.3739973625246
]
},
"workspace_info": {
"id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
},
"node_versions": {
- "CogVideoX-Fun": "235039911acf7b9d614b797dafe2230318d39a80",
+ "CogVideoX-Fun": "717f0629175ad192927dc51ec95c4376816a4212",
"ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e"
}
},
diff --git a/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_pose_ref.json b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_pose_ref.json
new file mode 100644
index 0000000..dfb5949
--- /dev/null
+++ b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_pose_ref.json
@@ -0,0 +1,742 @@
+{
+ "last_node_id": 103,
+ "last_link_id": 81,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": {
+ "0": -111.46612548828125,
+ "1": 460.2178955078125
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": {
+ "0": -99,
+ "1": 197
+ },
+ "size": {
+ "0": 326.1556091308594,
+ "1": 145.20904541015625
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": {
+ "0": -192,
+ "1": -293
+ },
+ "size": {
+ "0": 427.074951171875,
+ "1": 143.9142608642578
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 258,
+ "1": 178
+ },
+ "size": {
+ "0": 368.5529479980469,
+ "1": 159.4075927734375
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 78
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1488,
+ "1": 8
+ },
+ "size": [
+ 390.9534912109375,
+ 942.2558186848959
+ ],
+ "flags": {},
+ "order": 12,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 81,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00049.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 99,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1005,
+ "1": 554
+ },
+ "size": [
+ 315,
+ 849.46875
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 73,
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun-Preprocess-Video",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 19,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun-Preprocess-Video_00007.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 101,
+ "type": "VideoToOpenpose",
+ "pos": {
+ "0": 558,
+ "1": 474
+ },
+ "size": {
+ "0": 315,
+ "1": 58
+ },
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "input_video",
+ "type": "IMAGE",
+ "link": 72
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 73,
+ 79
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VideoToOpenpose"
+ },
+ "widgets_values": [
+ 81
+ ]
+ },
+ {
+ "id": 102,
+ "type": "LoadImage",
+ "pos": {
+ "0": 553,
+ "1": 598
+ },
+ "size": {
+ "0": 315,
+ "1": 314
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 80
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "9.png",
+ "image"
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 76
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 254,
+ "1": -46
+ },
+ "size": {
+ "0": 380.845703125,
+ "1": 157.68350219726562
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 77
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "一位动漫风格的女孩。她有着紫色的短发,头上戴着一个黑色和金色相间的蝴蝶结。她的表情显得有些严肃或沉思,眼睛大而有神。女孩穿着一件白色衬衫,外面搭配了一件深蓝色的背心,背心上有一个粉色的蝴蝶结装饰。她的裙子是白色的,裙摆蓬松,整体造型非常可爱且精致。背景是一个简单的圆形图案,颜色为粉红色和灰色相间,给人一种柔和的感觉。整个画面色调柔和,人物形象生动鲜明。"
+ ]
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": {
+ "0": 207.79391479492188,
+ "1": 473.83123779296875
+ },
+ "size": [
+ 252.056640625,
+ 688.5451388888889
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 72
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "000007.mp4",
+ "force_rate": 16,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 16,
+ "filename": "000007.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 103,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 996,
+ "1": 9
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 76
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 77
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 78
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 79,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": 80,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 81
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ ""
+ ]
+ }
+ ],
+ "links": [
+ [
+ 72,
+ 85,
+ 0,
+ 101,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 73,
+ 101,
+ 0,
+ 99,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 76,
+ 95,
+ 0,
+ 103,
+ 0,
+ "FunModels"
+ ],
+ [
+ 77,
+ 92,
+ 0,
+ 103,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 78,
+ 94,
+ 0,
+ 103,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 79,
+ 101,
+ 0,
+ 103,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 80,
+ 102,
+ 0,
+ 103,
+ 6,
+ "IMAGE"
+ ],
+ [
+ 81,
+ 103,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Upload Your Video And Reference Image",
+ "bounding": [
+ 91,
+ 383,
+ 859,
+ 841
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load EasyAnimate",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.6830134553650709,
+ "offset": [
+ 246.99418774865902,
+ 428.7658411125245
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "CogVideoX-Fun": "717f0629175ad192927dc51ec95c4376816a4212",
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "comfy-core": "v0.2.7-3-g8afb97c"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_ref.json b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_ref.json
new file mode 100644
index 0000000..497477c
--- /dev/null
+++ b/comfyui/wan2_1_fun/v1/wan2.1_fun_workflow_v2v_control_ref.json
@@ -0,0 +1,614 @@
+{
+ "last_node_id": 98,
+ "last_link_id": 67,
+ "nodes": [
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": {
+ "0": 18,
+ "1": -46
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": {
+ "0": 15.145149230957031,
+ "1": 527.0673217773438
+ },
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 88,
+ "type": "Note",
+ "pos": {
+ "0": -99,
+ "1": 197
+ },
+ "size": {
+ "0": 326.1556091308594,
+ "1": 145.20904541015625
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Using longer neg prompt such as \"Blurring, mutation, deformation, distortion, dark and solid, comics.\" can increase stability. Adding words such as \"quiet, solid\" to the neg prompt can increase dynamism.\n(使用更长的neg prompt如\"模糊,突变,变形,失真,画面暗,画面固定,连环画,漫画,线稿,没有主体。\",可以增加稳定性。在neg prompt中添加\"安静,固定\"等词语可以增加动态性。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 89,
+ "type": "Note",
+ "pos": {
+ "0": -192,
+ "1": -293
+ },
+ "size": {
+ "0": 427.074951171875,
+ "1": 143.9142608642578
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [],
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "When using the 1.3B model, you can set GPU_memory_mode to model_cpu_offload for faster generation. When using the 14B model, you can use sequential_cpu_offload to save GPU memory during generation.\n(在使用1.3B模型时,可以设置GPU_memory_mode为model_cpu_offload进行更快速度的生成,在使用14B模型时,可以使用sequential_cpu_offload节省显存,进行生成。)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": {
+ "0": 334.4051513671875,
+ "1": 540.6806640625
+ },
+ "size": [
+ 252.056640625,
+ 688.5451388888889
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 65
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "pose.mp4",
+ "force_rate": 0,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 0,
+ "filename": "pose.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 94,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 258,
+ "1": 178
+ },
+ "size": {
+ "0": 368.5529479980469,
+ "1": 159.4075927734375
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 64
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": {
+ "0": 1274,
+ "1": -77
+ },
+ "size": [
+ 390.9534912109375,
+ 942.2558186848959
+ ],
+ "flags": {},
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 67,
+ "slot_index": 0,
+ "label": "图像",
+ "shape": 7
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "label": "音频",
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理",
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "slot_index": 0,
+ "shape": 3,
+ "label": "文件名"
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 16,
+ "loop_count": 0,
+ "filename_prefix": "Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "Fun_00051.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 16
+ }
+ }
+ }
+ },
+ {
+ "id": 92,
+ "type": "FunTextBox",
+ "pos": {
+ "0": 254,
+ "1": -46
+ },
+ "size": {
+ "0": 380.845703125,
+ "1": 157.68350219726562
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 63
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "FunTextBox"
+ },
+ "widgets_values": [
+ "一位动漫风格的女孩。她有着紫色的短发,头上戴着一个黑色和金色相间的蝴蝶结。她的表情显得有些严肃或沉思,眼睛大而有神。女孩穿着一件白色衬衫,外面搭配了一件深蓝色的背心,背心上有一个粉色的蝴蝶结装饰。她的裙子是白色的,裙摆蓬松,整体造型非常可爱且精致。背景是一个简单的圆形图案,颜色为粉红色和灰色相间,给人一种柔和的感觉。整个画面色调柔和,人物形象生动鲜明。"
+ ]
+ },
+ {
+ "id": 97,
+ "type": "LoadImage",
+ "pos": {
+ "0": 629,
+ "1": 553
+ },
+ "size": {
+ "0": 315,
+ "1": 314
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 66
+ ]
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "9.png",
+ "image"
+ ]
+ },
+ {
+ "id": 95,
+ "type": "LoadWanFunModel",
+ "pos": {
+ "0": 275,
+ "1": -309
+ },
+ "size": {
+ "0": 435.2322082519531,
+ "1": 154
+ },
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "links": [
+ 62
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadWanFunModel"
+ },
+ "widgets_values": [
+ "Wan2.1-Fun-V1.1-1.3B-Control",
+ "Control",
+ "model_cpu_offload",
+ "wan2.1/wan_civitai.yaml",
+ "bf16"
+ ]
+ },
+ {
+ "id": 98,
+ "type": "WanFunV2VSampler",
+ "pos": {
+ "0": 798,
+ "1": -77
+ },
+ "size": [
+ 428.4000244140625,
+ 486
+ ],
+ "flags": {},
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "funmodels",
+ "type": "FunModels",
+ "link": 62
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 63
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 64
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "control_video",
+ "type": "IMAGE",
+ "link": 65,
+ "shape": 7
+ },
+ {
+ "name": "start_image",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "ref_image",
+ "type": "IMAGE",
+ "link": 66,
+ "shape": 7
+ },
+ {
+ "name": "riflex_k",
+ "type": "RIFLEXT_ARGS",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "camera_conditions",
+ "type": "STRING",
+ "link": null,
+ "widget": {
+ "name": "camera_conditions"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 67
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "WanFunV2VSampler"
+ },
+ "widgets_values": [
+ 81,
+ 640,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 1.0,
+ "Flow",
+ 0.1,
+ true,
+ 5,
+ true,
+ ""
+ ]
+ }
+ ],
+ "links": [
+ [
+ 62,
+ 95,
+ 0,
+ 98,
+ 0,
+ "FunModels"
+ ],
+ [
+ 63,
+ 92,
+ 0,
+ 98,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 64,
+ 94,
+ 0,
+ 98,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 65,
+ 85,
+ 0,
+ 98,
+ 4,
+ "IMAGE"
+ ],
+ [
+ 66,
+ 97,
+ 0,
+ 98,
+ 6,
+ "IMAGE"
+ ],
+ [
+ 67,
+ 98,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Upload Your Video",
+ "bounding": [
+ 217,
+ 450,
+ 761,
+ 789
+ ],
+ "color": "#a1309b",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Load EasyAnimate",
+ "bounding": [
+ 218,
+ -387,
+ 542,
+ 248
+ ],
+ "color": "#b06634",
+ "font_size": 24,
+ "flags": {}
+ },
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917358,
+ "offset": [
+ 23.894387748659057,
+ 254.96144111252457
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ },
+ "node_versions": {
+ "ComfyUI-VideoHelperSuite": "70faa9bcef65932ab72e7404d6373fb300013a2e",
+ "CogVideoX-Fun": "a7fa7028d52498f13e983eba012a81ebcae24977",
+ "comfy-core": "v0.2.7-3-g8afb97c"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/examples/cogvideox_fun/post_infer.py b/examples/cogvideox_fun/post_infer.py
index 9311752..ca7cc64 100755
--- a/examples/cogvideox_fun/post_infer.py
+++ b/examples/cogvideox_fun/post_infer.py
@@ -142,7 +142,7 @@ if __name__ == '__main__':
# End of record time
# The calculated time difference is the execution time of the program, expressed in seconds / s
time_end = time.time()
- time_sum = (time_end - time_start) % 60
+ time_sum = (time_end - time_start)
print('# --------------------------------------------------------- #')
print(f'# Total expenditure: {time_sum}s')
print('# --------------------------------------------------------- #')
\ No newline at end of file
diff --git a/examples/cogvideox_fun/post_infer_queue.py b/examples/cogvideox_fun/post_infer_queue.py
index 37e840b..db1b243 100755
--- a/examples/cogvideox_fun/post_infer_queue.py
+++ b/examples/cogvideox_fun/post_infer_queue.py
@@ -137,7 +137,7 @@ if __name__ == '__main__':
# End of record time
# The calculated time difference is the execution time of the program, expressed in seconds / s
time_end = time.time()
- time_sum = (time_end - time_start) % 60
+ time_sum = (time_end - time_start)
print('# --------------------------------------------------------- #')
print(f'# Total expenditure: {time_sum}s')
print('# --------------------------------------------------------- #')
\ No newline at end of file
diff --git a/examples/cogvideox_fun/predict_i2v.py b/examples/cogvideox_fun/predict_i2v.py
index 5dc26d2..44e3b68 100755
--- a/examples/cogvideox_fun/predict_i2v.py
+++ b/examples/cogvideox_fun/predict_i2v.py
@@ -14,7 +14,7 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
for project_root in project_roots:
sys.path.insert(0, project_root) if project_root not in sys.path else None
-from videox_fun.dist import set_multi_gpus_devices
+from videox_fun.dist import set_multi_gpus_devices, shard_model
from videox_fun.models import (AutoencoderKLCogVideoX,
CogVideoXTransformer3DModel, T5EncoderModel,
T5Tokenizer)
@@ -41,6 +41,7 @@ GPU_memory_mode = "model_cpu_offload_and_qfloat8"
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
ulysses_degree = 1
ring_degree = 1
+fsdp_dit = False
# Config and model path
model_name = "models/Diffusion_Transformer/CogVideoX-Fun-V1.1-2b-InP"
@@ -85,7 +86,7 @@ device = set_multi_gpus_devices(ulysses_degree, ring_degree)
transformer = CogVideoXTransformer3DModel.from_pretrained(
model_name,
subfolder="transformer",
- low_cpu_mem_usage=True,
+ low_cpu_mem_usage=True if not fsdp_dit else False,
torch_dtype=torch.float8_e4m3fn if GPU_memory_mode == "model_cpu_offload_and_qfloat8" else weight_dtype,
).to(weight_dtype)
@@ -158,7 +159,11 @@ else:
scheduler=scheduler,
)
if ulysses_degree > 1 or ring_degree > 1:
+ from functools import partial
transformer.enable_multi_gpus_inference()
+ if fsdp_dit:
+ shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
+ pipeline.transformer = shard_fn(pipeline.transformer)
if GPU_memory_mode == "sequential_cpu_offload":
pipeline.enable_sequential_cpu_offload(device=device)
diff --git a/examples/cogvideox_fun/predict_t2v.py b/examples/cogvideox_fun/predict_t2v.py
index b24c418..fa473d1 100755
--- a/examples/cogvideox_fun/predict_t2v.py
+++ b/examples/cogvideox_fun/predict_t2v.py
@@ -23,7 +23,7 @@ from videox_fun.pipeline import (CogVideoXFunPipeline,
from videox_fun.utils.fp8_optimization import convert_weight_dtype_wrapper
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
-from videox_fun.dist import set_multi_gpus_devices
+from videox_fun.dist import set_multi_gpus_devices, shard_model
# GPU memory mode, which can be choosen in [model_full_load, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
# model_full_load means that the entire model will be moved to the GPU.
@@ -42,6 +42,7 @@ GPU_memory_mode = "model_cpu_offload_and_qfloat8"
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
ulysses_degree = 1
ring_degree = 1
+fsdp_dit = False
# model path
model_name = "models/Diffusion_Transformer/CogVideoX-Fun-V1.1-2b-InP"
@@ -77,7 +78,7 @@ device = set_multi_gpus_devices(ulysses_degree, ring_degree)
transformer = CogVideoXTransformer3DModel.from_pretrained(
model_name,
subfolder="transformer",
- low_cpu_mem_usage=True,
+ low_cpu_mem_usage=True if not fsdp_dit else False,
torch_dtype=torch.float8_e4m3fn if GPU_memory_mode == "model_cpu_offload_and_qfloat8" else weight_dtype,
).to(weight_dtype)
@@ -150,7 +151,11 @@ else:
scheduler=scheduler,
)
if ulysses_degree > 1 or ring_degree > 1:
+ from functools import partial
transformer.enable_multi_gpus_inference()
+ if fsdp_dit:
+ shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
+ pipeline.transformer = shard_fn(pipeline.transformer)
if GPU_memory_mode == "sequential_cpu_offload":
pipeline.enable_sequential_cpu_offload(device=device)
diff --git a/examples/cogvideox_fun/predict_v2v.py b/examples/cogvideox_fun/predict_v2v.py
index 7e449f5..6f89660 100755
--- a/examples/cogvideox_fun/predict_v2v.py
+++ b/examples/cogvideox_fun/predict_v2v.py
@@ -22,7 +22,7 @@ from videox_fun.pipeline import (CogVideoXFunPipeline,
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
from videox_fun.utils.fp8_optimization import convert_weight_dtype_wrapper
from videox_fun.utils.utils import get_video_to_video_latent, save_videos_grid
-from videox_fun.dist import set_multi_gpus_devices
+from videox_fun.dist import set_multi_gpus_devices, shard_model
# GPU memory mode, which can be choosen in [model_full_load, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
# model_full_load means that the entire model will be moved to the GPU.
@@ -41,6 +41,7 @@ GPU_memory_mode = "model_cpu_offload_and_qfloat8"
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
ulysses_degree = 1
ring_degree = 1
+fsdp_dit = False
# model path
model_name = "models/Diffusion_Transformer/CogVideoX-Fun-V1.1-2b-InP"
@@ -84,7 +85,7 @@ device = set_multi_gpus_devices(ulysses_degree, ring_degree)
transformer = CogVideoXTransformer3DModel.from_pretrained(
model_name,
subfolder="transformer",
- low_cpu_mem_usage=True,
+ low_cpu_mem_usage=True if not fsdp_dit else False,
torch_dtype=torch.float8_e4m3fn if GPU_memory_mode == "model_cpu_offload_and_qfloat8" else weight_dtype,
).to(weight_dtype)
@@ -157,7 +158,11 @@ else:
scheduler=scheduler,
)
if ulysses_degree > 1 or ring_degree > 1:
+ from functools import partial
transformer.enable_multi_gpus_inference()
+ if fsdp_dit:
+ shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
+ pipeline.transformer = shard_fn(pipeline.transformer)
if GPU_memory_mode == "sequential_cpu_offload":
pipeline.enable_sequential_cpu_offload(device=device)
diff --git a/examples/cogvideox_fun/predict_v2v_control.py b/examples/cogvideox_fun/predict_v2v_control.py
index 5e8dd96..5fec551 100755
--- a/examples/cogvideox_fun/predict_v2v_control.py
+++ b/examples/cogvideox_fun/predict_v2v_control.py
@@ -24,7 +24,7 @@ from videox_fun.pipeline import (CogVideoXFunControlPipeline,
from videox_fun.utils.fp8_optimization import convert_weight_dtype_wrapper
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
from videox_fun.utils.utils import get_video_to_video_latent, save_videos_grid
-from videox_fun.dist import set_multi_gpus_devices
+from videox_fun.dist import set_multi_gpus_devices, shard_model
# GPU memory mode, which can be choosen in [model_full_load, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
# model_full_load means that the entire model will be moved to the GPU.
@@ -43,6 +43,7 @@ GPU_memory_mode = "model_cpu_offload_and_qfloat8"
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
ulysses_degree = 1
ring_degree = 1
+fsdp_dit = False
# model path
model_name = "models/Diffusion_Transformer/CogVideoX-Fun-V1.1-2b-Pose"
@@ -80,7 +81,7 @@ device = set_multi_gpus_devices(ulysses_degree, ring_degree)
transformer = CogVideoXTransformer3DModel.from_pretrained(
model_name,
subfolder="transformer",
- low_cpu_mem_usage=True,
+ low_cpu_mem_usage=True if not fsdp_dit else False,
torch_dtype=torch.float8_e4m3fn if GPU_memory_mode == "model_cpu_offload_and_qfloat8" else weight_dtype,
).to(weight_dtype)
@@ -144,7 +145,11 @@ pipeline = CogVideoXFunControlPipeline(
scheduler=scheduler,
)
if ulysses_degree > 1 or ring_degree > 1:
+ from functools import partial
transformer.enable_multi_gpus_inference()
+ if fsdp_dit:
+ shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
+ pipeline.transformer = shard_fn(pipeline.transformer)
if GPU_memory_mode == "sequential_cpu_offload":
pipeline.enable_sequential_cpu_offload(device=device)
diff --git a/examples/wan2.1/post_infer.py b/examples/wan2.1/post_infer.py
index e215a3a..0b973b7 100755
--- a/examples/wan2.1/post_infer.py
+++ b/examples/wan2.1/post_infer.py
@@ -142,7 +142,7 @@ if __name__ == '__main__':
# End of record time
# The calculated time difference is the execution time of the program, expressed in seconds / s
time_end = time.time()
- time_sum = (time_end - time_start) % 60
+ time_sum = (time_end - time_start)
print('# --------------------------------------------------------- #')
print(f'# Total expenditure: {time_sum}s')
print('# --------------------------------------------------------- #')
\ No newline at end of file
diff --git a/examples/wan2.1/post_infer_queue.py b/examples/wan2.1/post_infer_queue.py
index c046738..9ef89ad 100755
--- a/examples/wan2.1/post_infer_queue.py
+++ b/examples/wan2.1/post_infer_queue.py
@@ -137,7 +137,7 @@ if __name__ == '__main__':
# End of record time
# The calculated time difference is the execution time of the program, expressed in seconds / s
time_end = time.time()
- time_sum = (time_end - time_start) % 60
+ time_sum = (time_end - time_start)
print('# --------------------------------------------------------- #')
print(f'# Total expenditure: {time_sum}s')
print('# --------------------------------------------------------- #')
\ No newline at end of file
diff --git a/examples/wan2.1/post_infer_queue_i2v.py b/examples/wan2.1/post_infer_queue_i2v.py
index 14145cb..e907702 100755
--- a/examples/wan2.1/post_infer_queue_i2v.py
+++ b/examples/wan2.1/post_infer_queue_i2v.py
@@ -157,7 +157,7 @@ if __name__ == '__main__':
# End of record time
# The calculated time difference is the execution time of the program, expressed in seconds / s
time_end = time.time()
- time_sum = (time_end - time_start) % 60
+ time_sum = (time_end - time_start)
print('# --------------------------------------------------------- #')
print(f'# Total expenditure: {time_sum}s')
print('# --------------------------------------------------------- #')
diff --git a/examples/wan2.1/predict_i2v.py b/examples/wan2.1/predict_i2v.py
index 9bfd211..94bc73d 100755
--- a/examples/wan2.1/predict_i2v.py
+++ b/examples/wan2.1/predict_i2v.py
@@ -13,7 +13,7 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
for project_root in project_roots:
sys.path.insert(0, project_root) if project_root not in sys.path else None
-from videox_fun.dist import set_multi_gpus_devices
+from videox_fun.dist import set_multi_gpus_devices, shard_model
from videox_fun.models import (AutoencoderKLWan, AutoTokenizer, CLIPModel,
WanT5EncoderModel, WanTransformer3DModel)
from videox_fun.models.cache_utils import get_teacache_coefficients
@@ -43,6 +43,7 @@ GPU_memory_mode = "sequential_cpu_offload"
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
ulysses_degree = 1
ring_degree = 1
+fsdp_dit = False
# Support TeaCache.
enable_teacache = True
@@ -55,6 +56,10 @@ num_skip_start_steps = 5
# Whether to offload TeaCache tensors to cpu to save a little bit of GPU memory.
teacache_offload = False
+# Skip some cfg steps in inference
+# Recommended to be set between 0.00 and 0.25
+cfg_skip_ratio = 0
+
# Riflex config
enable_riflex = False
# Index of intrinsic frequency
@@ -65,8 +70,13 @@ config_path = "config/wan2.1/wan_civitai.yaml"
# model path
model_name = "models/Diffusion_Transformer/Wan2.1-I2V-14B-480P"
-# Choose the sampler in "Flow", "unipc", "dpm++"
+# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
sampler_name = "Flow"
+# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
+# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
+# If you want to generate a 480p video, it is recommended to set the shift value to 3.0.
+# If you want to generate a 720p video, it is recommended to set the shift value to 5.0.
+shift = 3
# Load pretrained model if need
transformer_path = None
@@ -77,7 +87,6 @@ lora_path = None
sample_size = [480, 832]
video_length = 81
fps = 16
-shift = 3 # Noise schedule shift parameter. Affects temporal dynamics. [NOTE]: If you want to generate a 480p video, it is recommended to set the shift value to 3.0.
# Use torch.float16 if GPU does not support torch.bfloat16
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
@@ -100,7 +109,7 @@ config = OmegaConf.load(config_path)
transformer = WanTransformer3DModel.from_pretrained(
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
- low_cpu_mem_usage=True,
+ low_cpu_mem_usage=True if not fsdp_dit else False,
torch_dtype=weight_dtype,
)
@@ -157,10 +166,10 @@ clip_image_encoder = clip_image_encoder.eval()
# Get Scheduler
Choosen_Scheduler = scheduler_dict = {
"Flow": FlowMatchEulerDiscreteScheduler,
- "unipc": FlowUniPCMultistepScheduler,
- "dpm++": FlowDPMSolverMultistepScheduler,
+ "Flow_Unipc": FlowUniPCMultistepScheduler,
+ "Flow_DPM++": FlowDPMSolverMultistepScheduler,
}[sampler_name]
-if sampler_name == "unipc" or sampler_name == "dpm++":
+if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
config['scheduler_kwargs']['shift'] = 1
scheduler = Choosen_Scheduler(
**filter_kwargs(Choosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
@@ -176,7 +185,11 @@ pipeline = WanI2VPipeline(
clip_image_encoder=clip_image_encoder
)
if ulysses_degree > 1 or ring_degree > 1:
+ from functools import partial
transformer.enable_multi_gpus_inference()
+ if fsdp_dit:
+ shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
+ pipeline.transformer = shard_fn(pipeline.transformer)
if GPU_memory_mode == "sequential_cpu_offload":
replace_parameters_by_name(transformer, ["modulation",], device=device)
@@ -225,6 +238,7 @@ with torch.no_grad():
video = input_video,
mask_video = input_video_mask,
clip_image = clip_image,
+ cfg_skip_ratio = cfg_skip_ratio,
shift = shift,
).videos
diff --git a/examples/wan2.1/predict_t2v.py b/examples/wan2.1/predict_t2v.py
index 7f06d23..82aea72 100755
--- a/examples/wan2.1/predict_t2v.py
+++ b/examples/wan2.1/predict_t2v.py
@@ -12,7 +12,7 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
for project_root in project_roots:
sys.path.insert(0, project_root) if project_root not in sys.path else None
-from videox_fun.dist import set_multi_gpus_devices
+from videox_fun.dist import set_multi_gpus_devices, shard_model
from videox_fun.models import (AutoencoderKLWan, WanT5EncoderModel, AutoTokenizer,
WanTransformer3DModel)
from videox_fun.models.cache_utils import get_teacache_coefficients
@@ -42,6 +42,7 @@ GPU_memory_mode = "sequential_cpu_offload"
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
ulysses_degree = 1
ring_degree = 1
+fsdp_dit = False
# TeaCache config
enable_teacache = True
@@ -54,6 +55,10 @@ num_skip_start_steps = 5
# Whether to offload TeaCache tensors to cpu to save a little bit of GPU memory.
teacache_offload = False
+# Skip some cfg steps in inference
+# Recommended to be set between 0.00 and 0.25
+cfg_skip_ratio = 0
+
# Riflex config
enable_riflex = False
# Index of intrinsic frequency
@@ -64,8 +69,13 @@ config_path = "config/wan2.1/wan_civitai.yaml"
# model path
model_name = "models/Diffusion_Transformer/Wan2.1-T2V-1.3B"
-# Choose the sampler in "Flow", "unipc", "dpm++"
+# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
sampler_name = "Flow"
+# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
+# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
+# If you want to generate a 480p video, it is recommended to set the shift value to 3.0.
+# If you want to generate a 720p video, it is recommended to set the shift value to 5.0.
+shift = 3
# Load pretrained model if need
transformer_path = None
@@ -76,7 +86,6 @@ lora_path = None
sample_size = [480, 832]
video_length = 81
fps = 16
-shift = 3 # Noise schedule shift parameter. Affects temporal dynamics. [NOTE]: If you want to generate a 480p video, it is recommended to set the shift value to 3.0.
# Use torch.float16 if GPU does not support torch.bfloat16
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
@@ -95,7 +104,7 @@ config = OmegaConf.load(config_path)
transformer = WanTransformer3DModel.from_pretrained(
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
- low_cpu_mem_usage=True,
+ low_cpu_mem_usage=True if not fsdp_dit else False,
torch_dtype=weight_dtype,
)
@@ -145,10 +154,10 @@ text_encoder = WanT5EncoderModel.from_pretrained(
# Get Scheduler
Choosen_Scheduler = scheduler_dict = {
"Flow": FlowMatchEulerDiscreteScheduler,
- "unipc": FlowUniPCMultistepScheduler,
- "dpm++": FlowDPMSolverMultistepScheduler,
+ "Flow_Unipc": FlowUniPCMultistepScheduler,
+ "Flow_DPM++": FlowDPMSolverMultistepScheduler,
}[sampler_name]
-if sampler_name == "unipc" or sampler_name == "dpm++":
+if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
config['scheduler_kwargs']['shift'] = 1
scheduler = Choosen_Scheduler(
**filter_kwargs(Choosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
@@ -163,7 +172,11 @@ pipeline = WanPipeline(
scheduler=scheduler,
)
if ulysses_degree > 1 or ring_degree > 1:
+ from functools import partial
transformer.enable_multi_gpus_inference()
+ if fsdp_dit:
+ shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
+ pipeline.transformer = shard_fn(pipeline.transformer)
if GPU_memory_mode == "sequential_cpu_offload":
replace_parameters_by_name(transformer, ["modulation",], device=device)
@@ -206,6 +219,7 @@ with torch.no_grad():
generator = generator,
guidance_scale = guidance_scale,
num_inference_steps = num_inference_steps,
+ cfg_skip_ratio = cfg_skip_ratio,
shift = shift,
).videos
diff --git a/examples/wan2.1_fun/app.py b/examples/wan2.1_fun/app.py
index a84b69f..a1b2226 100755
--- a/examples/wan2.1_fun/app.py
+++ b/examples/wan2.1_fun/app.py
@@ -62,7 +62,7 @@ if __name__ == "__main__":
config_path = "config/wan2.1/wan_civitai.yaml"
# Params below is used when ui_mode = "host"
# Model path of the pretrained model
- model_name = "models/Diffusion_Transformer/Wan2.1-Fun-1.3B-InP"
+ model_name = "models/Diffusion_Transformer/Wan2.1-Fun-V1.1-1.3B-InP"
# "Inpaint" or "Control"
model_type = "Inpaint"
diff --git a/examples/wan2.1_fun/launch_api.py b/examples/wan2.1_fun/launch_api.py
index f9d737a..a2ec2e2 100755
--- a/examples/wan2.1_fun/launch_api.py
+++ b/examples/wan2.1_fun/launch_api.py
@@ -31,7 +31,7 @@ def main():
parser.add_argument('--server_name', type=str, default="0.0.0.0", help='Server IP address')
parser.add_argument('--server_port', type=int, default=7860, help='Server Port')
parser.add_argument('--config_path', type=str, default="config/wan2.1/wan_civitai.yaml", help='Path to config file')
- parser.add_argument('--model_name', type=str, default="models/Diffusion_Transformer/Wan2.1-Fun-1.3B-InP", help='Model path')
+ parser.add_argument('--model_name', type=str, default="models/Diffusion_Transformer/Wan2.1-Fun-V1.1-1.3B-InP", help='Model path')
parser.add_argument('--model_type', type=str, default="Inpaint", help='Model type (Inpaint/Control)')
parser.add_argument('--savedir_sample', type=str, default=None, help='The save directory for samples')
args = parser.parse_args()
diff --git a/examples/wan2.1_fun/post_infer.py b/examples/wan2.1_fun/post_infer.py
index 770c3d8..9659c76 100755
--- a/examples/wan2.1_fun/post_infer.py
+++ b/examples/wan2.1_fun/post_infer.py
@@ -142,7 +142,7 @@ if __name__ == '__main__':
# End of record time
# The calculated time difference is the execution time of the program, expressed in seconds / s
time_end = time.time()
- time_sum = (time_end - time_start) % 60
+ time_sum = (time_end - time_start)
print('# --------------------------------------------------------- #')
print(f'# Total expenditure: {time_sum}s')
print('# --------------------------------------------------------- #')
\ No newline at end of file
diff --git a/examples/wan2.1_fun/post_infer_queue.py b/examples/wan2.1_fun/post_infer_queue.py
index c046738..9ef89ad 100755
--- a/examples/wan2.1_fun/post_infer_queue.py
+++ b/examples/wan2.1_fun/post_infer_queue.py
@@ -137,7 +137,7 @@ if __name__ == '__main__':
# End of record time
# The calculated time difference is the execution time of the program, expressed in seconds / s
time_end = time.time()
- time_sum = (time_end - time_start) % 60
+ time_sum = (time_end - time_start)
print('# --------------------------------------------------------- #')
print(f'# Total expenditure: {time_sum}s')
print('# --------------------------------------------------------- #')
\ No newline at end of file
diff --git a/examples/wan2.1_fun/post_infer_queue_i2v.py b/examples/wan2.1_fun/post_infer_queue_i2v.py
index 14145cb..0d80364 100755
--- a/examples/wan2.1_fun/post_infer_queue_i2v.py
+++ b/examples/wan2.1_fun/post_infer_queue_i2v.py
@@ -28,11 +28,12 @@ def post_infer(
):
if start_image:
try:
- image = Image.open(start_image)
- # 将图片转换为 Base64 编码
- buffered = BytesIO()
- image.save(buffered, format=image.format)
- start_image = base64.b64encode(buffered.getvalue()).decode('utf-8')
+ if not start_image.startswith("http"):
+ image = Image.open(start_image)
+ # 将图片转换为 Base64 编码
+ buffered = BytesIO()
+ image.save(buffered, format=image.format)
+ start_image = base64.b64encode(buffered.getvalue()).decode('utf-8')
except Exception as e:
print(f"Error processing start_image: {e}")
raise
@@ -157,7 +158,7 @@ if __name__ == '__main__':
# End of record time
# The calculated time difference is the execution time of the program, expressed in seconds / s
time_end = time.time()
- time_sum = (time_end - time_start) % 60
+ time_sum = (time_end - time_start)
print('# --------------------------------------------------------- #')
print(f'# Total expenditure: {time_sum}s')
print('# --------------------------------------------------------- #')
diff --git a/examples/wan2.1_fun/post_infer_queue_v2v_control.py b/examples/wan2.1_fun/post_infer_queue_v2v_control.py
index f3bff0a..ce0f4b3 100755
--- a/examples/wan2.1_fun/post_infer_queue_v2v_control.py
+++ b/examples/wan2.1_fun/post_infer_queue_v2v_control.py
@@ -154,7 +154,7 @@ if __name__ == '__main__':
# End of record time
# The calculated time difference is the execution time of the program, expressed in seconds / s
time_end = time.time()
- time_sum = (time_end - time_start) % 60
+ time_sum = (time_end - time_start)
print('# --------------------------------------------------------- #')
print(f'# Total expenditure: {time_sum}s')
print('# --------------------------------------------------------- #')
diff --git a/examples/wan2.1_fun/predict_i2v.py b/examples/wan2.1_fun/predict_i2v.py
index 3235ba9..8ea68a6 100755
--- a/examples/wan2.1_fun/predict_i2v.py
+++ b/examples/wan2.1_fun/predict_i2v.py
@@ -13,7 +13,7 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
for project_root in project_roots:
sys.path.insert(0, project_root) if project_root not in sys.path else None
-from videox_fun.dist import set_multi_gpus_devices
+from videox_fun.dist import set_multi_gpus_devices, shard_model
from videox_fun.models import (AutoencoderKLWan, CLIPModel, WanT5EncoderModel,
WanTransformer3DModel)
from videox_fun.models.cache_utils import get_teacache_coefficients
@@ -43,6 +43,7 @@ GPU_memory_mode = "sequential_cpu_offload"
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
ulysses_degree = 1
ring_degree = 1
+fsdp_dit = False
# Support TeaCache.
enable_teacache = True
@@ -55,6 +56,10 @@ num_skip_start_steps = 5
# Whether to offload TeaCache tensors to cpu to save a little bit of GPU memory.
teacache_offload = False
+# Skip some cfg steps in inference
+# Recommended to be set between 0.00 and 0.25
+cfg_skip_ratio = 0
+
# Riflex config
enable_riflex = False
# Index of intrinsic frequency
@@ -63,10 +68,15 @@ riflex_k = 6
# Config and model path
config_path = "config/wan2.1/wan_civitai.yaml"
# model path
-model_name = "models/Diffusion_Transformer/Wan2.1-Fun-1.3B-InP"
+model_name = "models/Diffusion_Transformer/Wan2.1-Fun-V1.1-1.3B-InP"
-# Choose the sampler in "Flow", "unipc", "dpm++"
+# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
sampler_name = "Flow"
+# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
+# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
+# If you want to generate a 480p video, it is recommended to set the shift value to 3.0.
+# If you want to generate a 720p video, it is recommended to set the shift value to 5.0.
+shift = 3
# Load pretrained model if need
transformer_path = None
@@ -77,7 +87,6 @@ lora_path = None
sample_size = [480, 832]
video_length = 81
fps = 16
-shift = 3 # Noise schedule shift parameter. Affects temporal dynamics. [NOTE]: If you want to generate a 480p video, it is recommended to set the shift value to 3.0.
# Use torch.float16 if GPU does not support torch.bfloat16
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
@@ -101,7 +110,7 @@ config = OmegaConf.load(config_path)
transformer = WanTransformer3DModel.from_pretrained(
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
- low_cpu_mem_usage=True,
+ low_cpu_mem_usage=True if not fsdp_dit else False,
torch_dtype=weight_dtype,
)
@@ -158,10 +167,10 @@ clip_image_encoder = clip_image_encoder.eval()
# Get Scheduler
Choosen_Scheduler = scheduler_dict = {
"Flow": FlowMatchEulerDiscreteScheduler,
- "unipc": FlowUniPCMultistepScheduler,
- "dpm++": FlowDPMSolverMultistepScheduler,
+ "Flow_Unipc": FlowUniPCMultistepScheduler,
+ "Flow_DPM++": FlowDPMSolverMultistepScheduler,
}[sampler_name]
-if sampler_name == "unipc" or sampler_name == "dpm++":
+if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
config['scheduler_kwargs']['shift'] = 1
scheduler = Choosen_Scheduler(
**filter_kwargs(Choosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
@@ -177,7 +186,11 @@ pipeline = WanFunInpaintPipeline(
clip_image_encoder=clip_image_encoder
)
if ulysses_degree > 1 or ring_degree > 1:
+ from functools import partial
transformer.enable_multi_gpus_inference()
+ if fsdp_dit:
+ shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
+ pipeline.transformer = shard_fn(pipeline.transformer)
if GPU_memory_mode == "sequential_cpu_offload":
replace_parameters_by_name(transformer, ["modulation",], device=device)
@@ -226,6 +239,7 @@ with torch.no_grad():
video = input_video,
mask_video = input_video_mask,
clip_image = clip_image,
+ cfg_skip_ratio = cfg_skip_ratio,
shift = shift,
).videos
diff --git a/examples/wan2.1_fun/predict_t2v.py b/examples/wan2.1_fun/predict_t2v.py
index 0035aba..134c3cc 100755
--- a/examples/wan2.1_fun/predict_t2v.py
+++ b/examples/wan2.1_fun/predict_t2v.py
@@ -13,7 +13,7 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
for project_root in project_roots:
sys.path.insert(0, project_root) if project_root not in sys.path else None
-from videox_fun.dist import set_multi_gpus_devices
+from videox_fun.dist import set_multi_gpus_devices, shard_model
from videox_fun.models import (AutoencoderKLWan, CLIPModel, WanT5EncoderModel,
WanTransformer3DModel)
from videox_fun.models.cache_utils import get_teacache_coefficients
@@ -43,6 +43,7 @@ GPU_memory_mode = "sequential_cpu_offload"
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
ulysses_degree = 1
ring_degree = 1
+fsdp_dit = False
# Support TeaCache.
enable_teacache = True
@@ -55,6 +56,10 @@ num_skip_start_steps = 5
# Whether to offload TeaCache tensors to cpu to save a little bit of GPU memory.
teacache_offload = False
+# Skip some cfg steps in inference
+# Recommended to be set between 0.00 and 0.25
+cfg_skip_ratio = 0
+
# Riflex config
enable_riflex = False
# Index of intrinsic frequency
@@ -63,10 +68,15 @@ riflex_k = 6
# Config and model path
config_path = "config/wan2.1/wan_civitai.yaml"
# model path
-model_name = "models/Diffusion_Transformer/Wan2.1-Fun-1.3B-InP"
+model_name = "models/Diffusion_Transformer/Wan2.1-Fun-V1.1-1.3B-InP"
-# Choose the sampler in "Flow", "unipc", "dpm++"
+# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
sampler_name = "Flow"
+# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
+# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
+# If you want to generate a 480p video, it is recommended to set the shift value to 3.0.
+# If you want to generate a 720p video, it is recommended to set the shift value to 5.0.
+shift = 3
# Load pretrained model if need
transformer_path = None
@@ -77,7 +87,6 @@ lora_path = None
sample_size = [480, 832]
video_length = 81
fps = 16
-shift = 3 # Noise schedule shift parameter. Affects temporal dynamics. [NOTE]: If you want to generate a 480p video, it is recommended to set the shift value to 3.0.
# Use torch.float16 if GPU does not support torch.bfloat16
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
@@ -96,7 +105,7 @@ config = OmegaConf.load(config_path)
transformer = WanTransformer3DModel.from_pretrained(
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
- low_cpu_mem_usage=True,
+ low_cpu_mem_usage=True if not fsdp_dit else False,
torch_dtype=weight_dtype,
)
@@ -157,10 +166,10 @@ else:
# Get Scheduler
Choosen_Scheduler = scheduler_dict = {
"Flow": FlowMatchEulerDiscreteScheduler,
- "unipc": FlowUniPCMultistepScheduler,
- "dpm++": FlowDPMSolverMultistepScheduler,
+ "Flow_Unipc": FlowUniPCMultistepScheduler,
+ "Flow_DPM++": FlowDPMSolverMultistepScheduler,
}[sampler_name]
-if sampler_name == "unipc" or sampler_name == "dpm++":
+if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
config['scheduler_kwargs']['shift'] = 1
scheduler = Choosen_Scheduler(
**filter_kwargs(Choosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
@@ -184,7 +193,11 @@ else:
scheduler=scheduler,
)
if ulysses_degree > 1 or ring_degree > 1:
+ from functools import partial
transformer.enable_multi_gpus_inference()
+ if fsdp_dit:
+ shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
+ pipeline.transformer = shard_fn(pipeline.transformer)
if GPU_memory_mode == "sequential_cpu_offload":
replace_parameters_by_name(transformer, ["modulation",], device=device)
@@ -233,6 +246,7 @@ with torch.no_grad():
video = input_video,
mask_video = input_video_mask,
+ cfg_skip_ratio = cfg_skip_ratio,
shift = shift,
).videos
else:
@@ -245,6 +259,7 @@ with torch.no_grad():
generator = generator,
guidance_scale = guidance_scale,
num_inference_steps = num_inference_steps,
+ cfg_skip_ratio = cfg_skip_ratio,
shift = shift,
).videos
diff --git a/examples/wan2.1_fun/predict_v2v_control.py b/examples/wan2.1_fun/predict_v2v_control.py
index 58b4eba..e59c95e 100755
--- a/examples/wan2.1_fun/predict_v2v_control.py
+++ b/examples/wan2.1_fun/predict_v2v_control.py
@@ -13,16 +13,17 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
for project_root in project_roots:
sys.path.insert(0, project_root) if project_root not in sys.path else None
-from videox_fun.dist import set_multi_gpus_devices
+from videox_fun.dist import set_multi_gpus_devices, shard_model
from videox_fun.models import (AutoencoderKLWan, AutoTokenizer, CLIPModel,
WanT5EncoderModel, WanTransformer3DModel)
+from videox_fun.data.dataset_image_video import process_pose_file
from videox_fun.models.cache_utils import get_teacache_coefficients
from videox_fun.pipeline import WanFunControlPipeline, WanPipeline
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
convert_weight_dtype_wrapper,
replace_parameters_by_name)
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
-from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
+from videox_fun.utils.utils import (filter_kwargs, get_image_latent,
get_video_to_video_latent,
save_videos_grid)
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
@@ -45,6 +46,7 @@ GPU_memory_mode = "sequential_cpu_offload"
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
ulysses_degree = 1
ring_degree = 1
+fsdp_dit = False
# Support TeaCache.
enable_teacache = True
@@ -57,6 +59,10 @@ num_skip_start_steps = 5
# Whether to offload TeaCache tensors to cpu to save a little bit of GPU memory.
teacache_offload = False
+# Skip some cfg steps in inference
+# Recommended to be set between 0.00 and 0.25
+cfg_skip_ratio = 0
+
# Riflex config
enable_riflex = False
# Index of intrinsic frequency
@@ -65,10 +71,15 @@ riflex_k = 6
# Config and model path
config_path = "config/wan2.1/wan_civitai.yaml"
# model path
-model_name = "models/Diffusion_Transformer/Wan2.1-Fun-1.3B-Control"
+model_name = "models/Diffusion_Transformer/Wan2.1-Fun-V1.1-1.3B-Control"
-# Choose the sampler in "Flow", "unipc", "dpm++"
+# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
sampler_name = "Flow"
+# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
+# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
+# If you want to generate a 480p video, it is recommended to set the shift value to 3.0.
+# If you want to generate a 720p video, it is recommended to set the shift value to 5.0.
+shift = 3
# Load pretrained model if need
transformer_path = None
@@ -79,12 +90,13 @@ lora_path = None
sample_size = [832, 480]
video_length = 49
fps = 16
-shift = 3 # Noise schedule shift parameter. Affects temporal dynamics. [NOTE]: If you want to generate a 480p video, it is recommended to set the shift value to 3.0.
# Use torch.float16 if GPU does not support torch.bfloat16
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
weight_dtype = torch.bfloat16
control_video = "asset/pose.mp4"
+control_camera_txt = None
+start_image = None
ref_image = None
# 使用更长的neg prompt如"模糊,突变,变形,失真,画面暗,文本字幕,画面固定,连环画,漫画,线稿,没有主体。",可以增加稳定性
@@ -108,7 +120,7 @@ config = OmegaConf.load(config_path)
transformer = WanTransformer3DModel.from_pretrained(
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
- low_cpu_mem_usage=True,
+ low_cpu_mem_usage=True if not fsdp_dit else False,
torch_dtype=weight_dtype,
)
@@ -165,10 +177,10 @@ clip_image_encoder = clip_image_encoder.eval()
# Get Scheduler
Choosen_Scheduler = scheduler_dict = {
"Flow": FlowMatchEulerDiscreteScheduler,
- "unipc": FlowUniPCMultistepScheduler,
- "dpm++": FlowDPMSolverMultistepScheduler,
+ "Flow_Unipc": FlowUniPCMultistepScheduler,
+ "Flow_DPM++": FlowDPMSolverMultistepScheduler,
}[sampler_name]
-if sampler_name == "unipc" or sampler_name == "dpm++":
+if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
config['scheduler_kwargs']['shift'] = 1
scheduler = Choosen_Scheduler(
**filter_kwargs(Choosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
@@ -184,7 +196,11 @@ pipeline = WanFunControlPipeline(
clip_image_encoder=clip_image_encoder
)
if ulysses_degree > 1 or ring_degree > 1:
+ from functools import partial
transformer.enable_multi_gpus_inference()
+ if fsdp_dit:
+ shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
+ pipeline.transformer = shard_fn(pipeline.transformer)
if GPU_memory_mode == "sequential_cpu_offload":
replace_parameters_by_name(transformer, ["modulation",], device=device)
@@ -217,8 +233,27 @@ with torch.no_grad():
if enable_riflex:
pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
+
+ if ref_image is not None:
+ clip_image = Image.open(ref_image).convert("RGB")
+ elif start_image is not None:
+ clip_image = Image.open(start_image).convert("RGB")
+ else:
+ clip_image = None
+
+ if ref_image is not None:
+ ref_image = get_image_latent(ref_image, sample_size=sample_size)
+
+ if start_image is not None:
+ start_image = get_image_latent(start_image, sample_size=sample_size)
- input_video, input_video_mask, ref_image, clip_image = get_video_to_video_latent(control_video, video_length=video_length, sample_size=sample_size, fps=fps, ref_image=ref_image)
+ if control_camera_txt is not None:
+ input_video, input_video_mask = None, None
+ control_camera_video = process_pose_file(control_camera_txt, sample_size[1], sample_size[0])
+ control_camera_video = control_camera_video[:video_length].permute([3, 0, 1, 2]).unsqueeze(0)
+ else:
+ input_video, input_video_mask, _, _ = get_video_to_video_latent(control_video, video_length=video_length, sample_size=sample_size, fps=fps, ref_image=None)
+ control_camera_video = None
sample = pipeline(
prompt,
@@ -231,8 +266,11 @@ with torch.no_grad():
num_inference_steps = num_inference_steps,
control_video = input_video,
+ control_camera_video = control_camera_video,
ref_image = ref_image,
+ start_image = start_image,
clip_image = clip_image,
+ cfg_skip_ratio = cfg_skip_ratio,
shift = shift,
).videos
diff --git a/examples/wan2.1_fun/predict_v2v_control_camera.py b/examples/wan2.1_fun/predict_v2v_control_camera.py
new file mode 100755
index 0000000..6e10175
--- /dev/null
+++ b/examples/wan2.1_fun/predict_v2v_control_camera.py
@@ -0,0 +1,303 @@
+import os
+import sys
+
+import numpy as np
+import torch
+from diffusers import FlowMatchEulerDiscreteScheduler
+from omegaconf import OmegaConf
+from PIL import Image
+from transformers import AutoTokenizer
+
+current_file_path = os.path.abspath(__file__)
+project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
+for project_root in project_roots:
+ sys.path.insert(0, project_root) if project_root not in sys.path else None
+
+from videox_fun.dist import set_multi_gpus_devices, shard_model
+from videox_fun.models import (AutoencoderKLWan, AutoTokenizer, CLIPModel,
+ WanT5EncoderModel, WanTransformer3DModel)
+from videox_fun.data.dataset_image_video import process_pose_file
+from videox_fun.models.cache_utils import get_teacache_coefficients
+from videox_fun.pipeline import WanFunControlPipeline, WanPipeline
+from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
+ convert_weight_dtype_wrapper,
+ replace_parameters_by_name)
+from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
+from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent, get_image_latent,
+ get_video_to_video_latent,
+ save_videos_grid)
+from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
+from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
+
+# GPU memory mode, which can be choosen in [model_full_load, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
+# model_full_load means that the entire model will be moved to the GPU.
+#
+# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
+#
+# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
+# and the transformer model has been quantized to float8, which can save more GPU memory.
+#
+# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
+# resulting in slower speeds but saving a large amount of GPU memory.
+GPU_memory_mode = "sequential_cpu_offload"
+# Multi GPUs config
+# Please ensure that the product of ulysses_degree and ring_degree equals the number of GPUs used.
+# For example, if you are using 8 GPUs, you can set ulysses_degree = 2 and ring_degree = 4.
+# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
+ulysses_degree = 1
+ring_degree = 1
+fsdp_dit = False
+
+# Support TeaCache.
+enable_teacache = True
+# Recommended to be set between 0.05 and 0.20. A larger threshold can cache more steps, speeding up the inference process,
+# but it may cause slight differences between the generated content and the original content.
+teacache_threshold = 0.10
+# The number of steps to skip TeaCache at the beginning of the inference process, which can
+# reduce the impact of TeaCache on generated video quality.
+num_skip_start_steps = 5
+# Whether to offload TeaCache tensors to cpu to save a little bit of GPU memory.
+teacache_offload = False
+
+# Skip some cfg steps in inference
+# Recommended to be set between 0.00 and 0.25
+cfg_skip_ratio = 0
+
+# Riflex config
+enable_riflex = False
+# Index of intrinsic frequency
+riflex_k = 6
+
+# Config and model path
+config_path = "config/wan2.1/wan_civitai.yaml"
+# model path
+model_name = "models/Diffusion_Transformer/Wan2.1-Fun-V1.1-1.3B-Control-Camera"
+
+# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
+sampler_name = "Flow"
+# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
+# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
+# If you want to generate a 480p video, it is recommended to set the shift value to 3.0.
+# If you want to generate a 720p video, it is recommended to set the shift value to 5.0.
+shift = 3
+
+# Load pretrained model if need
+transformer_path = None
+vae_path = None
+lora_path = None
+
+# Other params
+sample_size = [480, 832]
+video_length = 81
+fps = 16
+
+# Use torch.float16 if GPU does not support torch.bfloat16
+# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
+weight_dtype = torch.bfloat16
+control_video = None
+control_camera_txt = "asset/Pan_Left.txt"
+start_image = "asset/7.png"
+ref_image = None
+
+# 使用更长的neg prompt如"模糊,突变,变形,失真,画面暗,文本字幕,画面固定,连环画,漫画,线稿,没有主体。",可以增加稳定性
+# 在neg prompt中添加"安静,固定"等词语可以增加动态性。
+prompt = "一个小女孩正在户外玩耍。她穿着一件蓝色的短袖上衣和粉色的短裤,头发扎成一个可爱的辫子。她的脚上没有穿鞋,显得非常自然和随意。她正用一把红色的小铲子在泥土里挖土,似乎在进行某种有趣的活动,可能是种花或是挖掘宝藏。地上有一根长长的水管,可能是用来浇水的。背景是一片草地和一些绿色植物,阳光明媚,整个场景充满了童趣和生机。小女孩专注的表情和认真的动作让人感受到她的快乐和好奇心。"
+negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+
+# Using longer neg prompt such as "Blurring, mutation, deformation, distortion, dark and solid, comics, text subtitles, line art." can increase stability
+# Adding words such as "quiet, solid" to the neg prompt can increase dynamism.
+# prompt = "A young woman with beautiful, clear eyes and blonde hair stands in the forest, wearing a white dress and a crown. Her expression is serene, reminiscent of a movie star, with fair and youthful skin. Her brown long hair flows in the wind. The video quality is very high, with a clear view. High quality, masterpiece, best quality, high resolution, ultra-fine, fantastical."
+# negative_prompt = "Twisted body, limb deformities, text captions, comic, static, ugly, error, messy code."
+guidance_scale = 6.0
+seed = 43
+num_inference_steps = 50
+lora_weight = 0.55
+save_path = "samples/wan-videos-fun-control"
+
+device = set_multi_gpus_devices(ulysses_degree, ring_degree)
+config = OmegaConf.load(config_path)
+
+transformer = WanTransformer3DModel.from_pretrained(
+ os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
+ transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
+ low_cpu_mem_usage=True if not fsdp_dit else False,
+ torch_dtype=weight_dtype,
+)
+
+if transformer_path is not None:
+ print(f"From checkpoint: {transformer_path}")
+ if transformer_path.endswith("safetensors"):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(transformer_path)
+ else:
+ state_dict = torch.load(transformer_path, map_location="cpu")
+ state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
+
+ m, u = transformer.load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+
+# Get Vae
+vae = AutoencoderKLWan.from_pretrained(
+ os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
+ additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
+).to(weight_dtype)
+
+if vae_path is not None:
+ print(f"From checkpoint: {vae_path}")
+ if vae_path.endswith("safetensors"):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(vae_path)
+ else:
+ state_dict = torch.load(vae_path, map_location="cpu")
+ state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
+
+ m, u = vae.load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+
+# Get Tokenizer
+tokenizer = AutoTokenizer.from_pretrained(
+ os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
+)
+
+# Get Text encoder
+text_encoder = WanT5EncoderModel.from_pretrained(
+ os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
+ additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
+ low_cpu_mem_usage=True,
+ torch_dtype=weight_dtype,
+)
+text_encoder = text_encoder.eval()
+
+# Get Clip Image Encoder
+clip_image_encoder = CLIPModel.from_pretrained(
+ os.path.join(model_name, config['image_encoder_kwargs'].get('image_encoder_subpath', 'image_encoder')),
+).to(weight_dtype)
+clip_image_encoder = clip_image_encoder.eval()
+
+# Get Scheduler
+Choosen_Scheduler = scheduler_dict = {
+ "Flow": FlowMatchEulerDiscreteScheduler,
+ "Flow_Unipc": FlowUniPCMultistepScheduler,
+ "Flow_DPM++": FlowDPMSolverMultistepScheduler,
+}[sampler_name]
+if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
+ config['scheduler_kwargs']['shift'] = 1
+scheduler = Choosen_Scheduler(
+ **filter_kwargs(Choosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
+)
+
+# Get Pipeline
+pipeline = WanFunControlPipeline(
+ transformer=transformer,
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ scheduler=scheduler,
+ clip_image_encoder=clip_image_encoder
+)
+if ulysses_degree > 1 or ring_degree > 1:
+ from functools import partial
+ transformer.enable_multi_gpus_inference()
+ if fsdp_dit:
+ shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
+ pipeline.transformer = shard_fn(pipeline.transformer)
+
+if GPU_memory_mode == "sequential_cpu_offload":
+ replace_parameters_by_name(transformer, ["modulation",], device=device)
+ transformer.freqs = transformer.freqs.to(device=device)
+ pipeline.enable_sequential_cpu_offload(device=device)
+elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
+ convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",])
+ convert_weight_dtype_wrapper(transformer, weight_dtype)
+ pipeline.enable_model_cpu_offload(device=device)
+elif GPU_memory_mode == "model_cpu_offload":
+ pipeline.enable_model_cpu_offload(device=device)
+else:
+ pipeline.to(device=device)
+
+coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
+if coefficients is not None:
+ print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
+ pipeline.transformer.enable_teacache(
+ coefficients, num_inference_steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
+ )
+
+generator = torch.Generator(device=device).manual_seed(seed)
+
+if lora_path is not None:
+ pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device)
+
+with torch.no_grad():
+ video_length = int((video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+ latent_frames = (video_length - 1) // vae.config.temporal_compression_ratio + 1
+
+ if enable_riflex:
+ pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
+
+ if ref_image is not None:
+ clip_image = Image.open(ref_image).convert("RGB")
+ elif start_image is not None:
+ clip_image = Image.open(start_image).convert("RGB")
+ else:
+ clip_image = None
+
+ if ref_image is not None:
+ ref_image = get_image_latent(ref_image, sample_size=sample_size)
+
+ if start_image is not None:
+ start_image = get_image_latent(start_image, sample_size=sample_size)
+
+ if control_camera_txt is not None:
+ input_video, input_video_mask = None, None
+ control_camera_video = process_pose_file(control_camera_txt, sample_size[1], sample_size[0])
+ control_camera_video = control_camera_video[:video_length].permute([3, 0, 1, 2]).unsqueeze(0)
+ else:
+ input_video, input_video_mask, _, _ = get_video_to_video_latent(control_video, video_length=video_length, sample_size=sample_size, fps=fps, ref_image=None)
+ control_camera_video = None
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = sample_size[0],
+ width = sample_size[1],
+ generator = generator,
+ guidance_scale = guidance_scale,
+ num_inference_steps = num_inference_steps,
+
+ control_video = input_video,
+ control_camera_video = control_camera_video,
+ ref_image = ref_image,
+ start_image = start_image,
+ clip_image = clip_image,
+ cfg_skip_ratio = cfg_skip_ratio,
+ shift = shift,
+ ).videos
+
+if lora_path is not None:
+ pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device)
+
+def save_results():
+ if not os.path.exists(save_path):
+ os.makedirs(save_path, exist_ok=True)
+
+ index = len([path for path in os.listdir(save_path)]) + 1
+ prefix = str(index).zfill(8)
+ if video_length == 1:
+ video_path = os.path.join(save_path, prefix + ".png")
+
+ image = sample[0, :, 0]
+ image = image.transpose(0, 1).transpose(1, 2)
+ image = (image * 255).numpy().astype(np.uint8)
+ image = Image.fromarray(image)
+ image.save(video_path)
+ else:
+ video_path = os.path.join(save_path, prefix + ".mp4")
+ save_videos_grid(sample, video_path, fps=fps)
+
+if ulysses_degree * ring_degree > 1:
+ import torch.distributed as dist
+ if dist.get_rank() == 0:
+ save_results()
+else:
+ save_results()
\ No newline at end of file
diff --git a/examples/wan2.1_fun/predict_v2v_control_ref.py b/examples/wan2.1_fun/predict_v2v_control_ref.py
new file mode 100755
index 0000000..51648ab
--- /dev/null
+++ b/examples/wan2.1_fun/predict_v2v_control_ref.py
@@ -0,0 +1,303 @@
+import os
+import sys
+
+import numpy as np
+import torch
+from diffusers import FlowMatchEulerDiscreteScheduler
+from omegaconf import OmegaConf
+from PIL import Image
+from transformers import AutoTokenizer
+
+current_file_path = os.path.abspath(__file__)
+project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
+for project_root in project_roots:
+ sys.path.insert(0, project_root) if project_root not in sys.path else None
+
+from videox_fun.dist import set_multi_gpus_devices, shard_model
+from videox_fun.models import (AutoencoderKLWan, AutoTokenizer, CLIPModel,
+ WanT5EncoderModel, WanTransformer3DModel)
+from videox_fun.data.dataset_image_video import process_pose_file
+from videox_fun.models.cache_utils import get_teacache_coefficients
+from videox_fun.pipeline import WanFunControlPipeline, WanPipeline
+from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
+ convert_weight_dtype_wrapper,
+ replace_parameters_by_name)
+from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
+from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent, get_image_latent,
+ get_video_to_video_latent,
+ save_videos_grid)
+from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
+from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
+
+# GPU memory mode, which can be choosen in [model_full_load, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
+# model_full_load means that the entire model will be moved to the GPU.
+#
+# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
+#
+# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
+# and the transformer model has been quantized to float8, which can save more GPU memory.
+#
+# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
+# resulting in slower speeds but saving a large amount of GPU memory.
+GPU_memory_mode = "sequential_cpu_offload"
+# Multi GPUs config
+# Please ensure that the product of ulysses_degree and ring_degree equals the number of GPUs used.
+# For example, if you are using 8 GPUs, you can set ulysses_degree = 2 and ring_degree = 4.
+# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
+ulysses_degree = 1
+ring_degree = 1
+fsdp_dit = False
+
+# Support TeaCache.
+enable_teacache = True
+# Recommended to be set between 0.05 and 0.20. A larger threshold can cache more steps, speeding up the inference process,
+# but it may cause slight differences between the generated content and the original content.
+teacache_threshold = 0.10
+# The number of steps to skip TeaCache at the beginning of the inference process, which can
+# reduce the impact of TeaCache on generated video quality.
+num_skip_start_steps = 5
+# Whether to offload TeaCache tensors to cpu to save a little bit of GPU memory.
+teacache_offload = False
+
+# Skip some cfg steps in inference for acceleration
+# Recommended to be set between 0.00 and 0.25
+cfg_skip_ratio = 0
+
+# Riflex config
+enable_riflex = False
+# Index of intrinsic frequency
+riflex_k = 6
+
+# Config and model path
+config_path = "config/wan2.1/wan_civitai.yaml"
+# model path
+model_name = "models/Diffusion_Transformer/Wan2.1-Fun-V1.1-1.3B-Control"
+
+# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
+sampler_name = "Flow"
+# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
+# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
+# If you want to generate a 480p video, it is recommended to set the shift value to 3.0.
+# If you want to generate a 720p video, it is recommended to set the shift value to 5.0.
+shift = 3
+
+# Load pretrained model if need
+transformer_path = None
+vae_path = None
+lora_path = None
+
+# Other params
+sample_size = [832, 480]
+video_length = 49
+fps = 16
+
+# Use torch.float16 if GPU does not support torch.bfloat16
+# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
+weight_dtype = torch.bfloat16
+control_video = "asset/pose.mp4"
+control_camera_txt = None
+start_image = None
+ref_image = "asset/6.png"
+
+# 使用更长的neg prompt如"模糊,突变,变形,失真,画面暗,文本字幕,画面固定,连环画,漫画,线稿,没有主体。",可以增加稳定性
+# 在neg prompt中添加"安静,固定"等词语可以增加动态性。
+prompt = "一位年轻女性穿着一件粉色的连衣裙,裙子上有白色的装饰和粉色的纽扣。她的头发是紫色的,头上戴着一个红色的大蝴蝶结,显得非常可爱和精致。她还戴着一个红色的领结,整体造型充满了少女感和活力。她的表情温柔,双手轻轻交叉放在身前,姿态优雅。背景是简单的灰色,没有任何多余的装饰,使得人物更加突出。她的妆容清淡自然,突显了她的清新气质。整体画面给人一种甜美、梦幻的感觉,仿佛置身于童话世界中。"
+negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
+
+# Using longer neg prompt such as "Blurring, mutation, deformation, distortion, dark and solid, comics, text subtitles, line art." can increase stability
+# Adding words such as "quiet, solid" to the neg prompt can increase dynamism.
+# prompt = "A young woman with beautiful, clear eyes and blonde hair stands in the forest, wearing a white dress and a crown. Her expression is serene, reminiscent of a movie star, with fair and youthful skin. Her brown long hair flows in the wind. The video quality is very high, with a clear view. High quality, masterpiece, best quality, high resolution, ultra-fine, fantastical."
+# negative_prompt = "Twisted body, limb deformities, text captions, comic, static, ugly, error, messy code."
+guidance_scale = 6.0
+seed = 43
+num_inference_steps = 50
+lora_weight = 0.55
+save_path = "samples/wan-videos-fun-control"
+
+device = set_multi_gpus_devices(ulysses_degree, ring_degree)
+config = OmegaConf.load(config_path)
+
+transformer = WanTransformer3DModel.from_pretrained(
+ os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
+ transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
+ low_cpu_mem_usage=True if not fsdp_dit else False,
+ torch_dtype=weight_dtype,
+)
+
+if transformer_path is not None:
+ print(f"From checkpoint: {transformer_path}")
+ if transformer_path.endswith("safetensors"):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(transformer_path)
+ else:
+ state_dict = torch.load(transformer_path, map_location="cpu")
+ state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
+
+ m, u = transformer.load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+
+# Get Vae
+vae = AutoencoderKLWan.from_pretrained(
+ os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
+ additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
+).to(weight_dtype)
+
+if vae_path is not None:
+ print(f"From checkpoint: {vae_path}")
+ if vae_path.endswith("safetensors"):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(vae_path)
+ else:
+ state_dict = torch.load(vae_path, map_location="cpu")
+ state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
+
+ m, u = vae.load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+
+# Get Tokenizer
+tokenizer = AutoTokenizer.from_pretrained(
+ os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
+)
+
+# Get Text encoder
+text_encoder = WanT5EncoderModel.from_pretrained(
+ os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
+ additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
+ low_cpu_mem_usage=True,
+ torch_dtype=weight_dtype,
+)
+text_encoder = text_encoder.eval()
+
+# Get Clip Image Encoder
+clip_image_encoder = CLIPModel.from_pretrained(
+ os.path.join(model_name, config['image_encoder_kwargs'].get('image_encoder_subpath', 'image_encoder')),
+).to(weight_dtype)
+clip_image_encoder = clip_image_encoder.eval()
+
+# Get Scheduler
+Choosen_Scheduler = scheduler_dict = {
+ "Flow": FlowMatchEulerDiscreteScheduler,
+ "Flow_Unipc": FlowUniPCMultistepScheduler,
+ "Flow_DPM++": FlowDPMSolverMultistepScheduler,
+}[sampler_name]
+if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
+ config['scheduler_kwargs']['shift'] = 1
+scheduler = Choosen_Scheduler(
+ **filter_kwargs(Choosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
+)
+
+# Get Pipeline
+pipeline = WanFunControlPipeline(
+ transformer=transformer,
+ vae=vae,
+ tokenizer=tokenizer,
+ text_encoder=text_encoder,
+ scheduler=scheduler,
+ clip_image_encoder=clip_image_encoder
+)
+if ulysses_degree > 1 or ring_degree > 1:
+ from functools import partial
+ transformer.enable_multi_gpus_inference()
+ if fsdp_dit:
+ shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
+ pipeline.transformer = shard_fn(pipeline.transformer)
+
+if GPU_memory_mode == "sequential_cpu_offload":
+ replace_parameters_by_name(transformer, ["modulation",], device=device)
+ transformer.freqs = transformer.freqs.to(device=device)
+ pipeline.enable_sequential_cpu_offload(device=device)
+elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
+ convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",])
+ convert_weight_dtype_wrapper(transformer, weight_dtype)
+ pipeline.enable_model_cpu_offload(device=device)
+elif GPU_memory_mode == "model_cpu_offload":
+ pipeline.enable_model_cpu_offload(device=device)
+else:
+ pipeline.to(device=device)
+
+coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
+if coefficients is not None:
+ print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
+ pipeline.transformer.enable_teacache(
+ coefficients, num_inference_steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
+ )
+
+generator = torch.Generator(device=device).manual_seed(seed)
+
+if lora_path is not None:
+ pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device)
+
+with torch.no_grad():
+ video_length = int((video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+ latent_frames = (video_length - 1) // vae.config.temporal_compression_ratio + 1
+
+ if enable_riflex:
+ pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
+
+ if ref_image is not None:
+ clip_image = Image.open(ref_image).convert("RGB")
+ elif start_image is not None:
+ clip_image = Image.open(start_image).convert("RGB")
+ else:
+ clip_image = None
+
+ if ref_image is not None:
+ ref_image = get_image_latent(ref_image, sample_size=sample_size)
+
+ if start_image is not None:
+ start_image = get_image_latent(start_image, sample_size=sample_size)
+
+ if control_camera_txt is not None:
+ input_video, input_video_mask = None, None
+ control_camera_video = process_pose_file(control_camera_txt, sample_size[1], sample_size[0])
+ control_camera_video = control_camera_video[:video_length].permute([3, 0, 1, 2]).unsqueeze(0)
+ else:
+ input_video, input_video_mask, _, _ = get_video_to_video_latent(control_video, video_length=video_length, sample_size=sample_size, fps=fps, ref_image=None)
+ control_camera_video = None
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = sample_size[0],
+ width = sample_size[1],
+ generator = generator,
+ guidance_scale = guidance_scale,
+ num_inference_steps = num_inference_steps,
+
+ control_video = input_video,
+ control_camera_video = control_camera_video,
+ ref_image = ref_image,
+ start_image = start_image,
+ clip_image = clip_image,
+ cfg_skip_ratio = cfg_skip_ratio,
+ shift = shift,
+ ).videos
+
+if lora_path is not None:
+ pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device)
+
+def save_results():
+ if not os.path.exists(save_path):
+ os.makedirs(save_path, exist_ok=True)
+
+ index = len([path for path in os.listdir(save_path)]) + 1
+ prefix = str(index).zfill(8)
+ if video_length == 1:
+ video_path = os.path.join(save_path, prefix + ".png")
+
+ image = sample[0, :, 0]
+ image = image.transpose(0, 1).transpose(1, 2)
+ image = (image * 255).numpy().astype(np.uint8)
+ image = Image.fromarray(image)
+ image.save(video_path)
+ else:
+ video_path = os.path.join(save_path, prefix + ".mp4")
+ save_videos_grid(sample, video_path, fps=fps)
+
+if ulysses_degree * ring_degree > 1:
+ import torch.distributed as dist
+ if dist.get_rank() == 0:
+ save_results()
+else:
+ save_results()
\ No newline at end of file
diff --git a/reports/report_v1.md b/reports/cogvideox_fun/report_v1.md
similarity index 100%
rename from reports/report_v1.md
rename to reports/cogvideox_fun/report_v1.md
diff --git a/reports/report_v1_1.md b/reports/cogvideox_fun/report_v1_1.md
similarity index 100%
rename from reports/report_v1_1.md
rename to reports/cogvideox_fun/report_v1_1.md
diff --git a/reports/report_v1_1_zh-CN.md b/reports/cogvideox_fun/report_v1_1_zh-CN.md
similarity index 100%
rename from reports/report_v1_1_zh-CN.md
rename to reports/cogvideox_fun/report_v1_1_zh-CN.md
diff --git a/reports/report_v1_zh-CN.md b/reports/cogvideox_fun/report_v1_zh-CN.md
similarity index 100%
rename from reports/report_v1_zh-CN.md
rename to reports/cogvideox_fun/report_v1_zh-CN.md
diff --git a/reports/wan2_1_fun/report_v1_1.md b/reports/wan2_1_fun/report_v1_1.md
new file mode 100644
index 0000000..3e724f5
--- /dev/null
+++ b/reports/wan2_1_fun/report_v1_1.md
@@ -0,0 +1,31 @@
+# Wan Fun v1.1 Report
+
+In Wan-Fun v1.1, we updated six models: the 14B Inpaint model, Control model, and Control-Camera model; as well as the 1.3B Inpaint model, Control model, and Control-Camera model.
+
+Compared to the previous version, the Inpaint model has been trained with a larger batch size, resulting in more stable performance. The Control model now includes a reference image model to achieve effects similar to Animate Anyone. While retaining its original functionality, it can also accept both a reference image and a control video as inputs for generation. Finally, we provide a camera control model that supports pan-and-tilt movements (left, right, up, down).
+
+Additionally, we have released training and inference code for adding reference control signals, as well as training and inference code for adding camera control signals.
+
+Compared to V1.0, Wan Fun V1.1 highlights the following features:
+
+- A more stable Inpaint model.
+- On top of the original control scheme, we’ve implemented a new control approach combining reference images and control videos.
+- Added support for a camera control model.
+
+## Implementation of Reference Image + Control Video
+In Wan-Fun V1.0, we already supported multiple control signals such as Canny, Depth, Pose, and MLSD, and implemented two control schemes: initial-image plus trajectory control, and control-video-guided generation.
+
+To further enhance the usability of the control model, we developed a new control scheme that combines reference images with control videos, akin to Animate Anyone. This feature takes a reference image as input and generates output based on control signals like Openpose (though it is not limited to Openpose—Depth signals also yield impressive results). Previously, methods like Unimate or Animate Anyone typically required the skeleton of the reference image to closely align with the control video. However, in Wan-Fun V1.1 Control, even if there is some misalignment, the system still produces acceptable results, though better alignment naturally leads to higher similarity.
+
+We encode the reference image using VAE, then tile the latent representation and concatenate the tiled features with the video features for generation. To ensure that this does not interfere with the model's original functionality, during training, we randomly initialize the reference image latent as all zeros to simulate cases where no reference image is provided. The overall workflow of the model is shown in the figure below:
+
+
+
+## Camera Control Model
+Building upon Wan-Fun V1.0, we now support additional camera information inputs for camera control.
+
+Inspired by [CameraCtrl](https://github.com/hehao13/CameraCtrl) and [EasyAnimate](https://github.com/aigc-apps/EasyAnimate), instead of directly resizing inputs like EasyAnimate does to input camera trajectories, we first use PixelUnshuffle to convert temporal information into channel information. Then, using an adapter mechanism, we transform the camera trajectory into high-level semantic information before adding it to the video features post-Conv. This allows us to achieve precise control over the camera lens movement.
+
+The overall framework of the model is shown in the figure below:
+
+
\ No newline at end of file
diff --git a/reports/wan2_1_fun/report_v1_1_zh-CN.md b/reports/wan2_1_fun/report_v1_1_zh-CN.md
new file mode 100644
index 0000000..0c81611
--- /dev/null
+++ b/reports/wan2_1_fun/report_v1_1_zh-CN.md
@@ -0,0 +1,31 @@
+# Wan Fun v1.1 Report
+
+在Wan-Fun v1.1中,我们更新了6个模型,分别是:14B的Inpaint模型,Control模型、Control-Camera模型;1.3B的Inpaint模型,Control模型、Control-Camera模型。
+
+相比于上一个版本,Inpaint模型经过了更大batch size的训练,模型效果的稳定性更优秀;Control模型则新增加了一个参考图模型,以实现类似于Animate Anyone的效果,在保留之前功能的基础上,我们可以同时传入参考图片和控制视频,以实现生成;最后我们提供了镜头控制模型,可以实现上下左右的镜头控制。
+
+另外,我们还发布了添加参考控制信号的训练代码与预测代码,添加镜头控制信号的训练代码和预测代码。
+
+对比V1.0版本,Wan Fun V1.1突出了以下功能:
+
+- 更为稳定的Inpaint模型。
+- 在原控制方案的基础上,实现了参考图加上控制视频的控制方案。
+- 实现了镜头控制模型。
+
+## 参考图加上控制视频的实现
+在原本Wan-Fun V1.0的中,我们已经支持了多种控制信号,如Canny、Depth、Pose、MLSD;实现了两种控制方案,如首图+轨迹控制、控制视频指导生成。
+
+为了进一步提高控制模型的可用性,我们进一步开发了参考图加上控制视频的控制方案,该功能animate anyone,输入一张参考图片,然后根据Openpose(并不局限于Openpose,Depth信号也有非常亮眼的效果)之类的控制实现生成。此前,Unimate、animate anyone之类的方案一般要求参考图和控制视频骨架基本对齐。在Wan-Fun V1.1 Control中,对齐可以有更好的相似度,不对齐也可以有一定的参考生成效果。
+
+我们将参考图使用VAE Encode之后,将latent平铺,然后将平铺后的特征与视频特征进行concat实现生成,为了不影响模型的原功能,我们在训练中随机将参考图latent初始化为全0,代表没有参考图输入,整体模型的工作框架如图所示:
+
+
+
+## 镜头控制模型
+在原本Wan-Fun V1.0的基础上,我们支持进一步输入Camera信息,以进行镜头控制。
+
+参考[CameraCtrl](https://github.com/hehao13/CameraCtrl)与[EasyAnimate](https://github.com/aigc-apps/EasyAnimate),我们没有选择类似于EasyAnimate那种直接Resize的方式输入相机镜头的控制轨迹,而是先使用PixelUnshuffle将时序信息转换成通道信息,然后使用Adapter的方式,将相机镜头的轨迹转换成高层语义信息后再与Conv in后的视频特征相加,从而实现了视频镜头的控制。
+
+整体模型的工作框架如图所示:
+
+
\ No newline at end of file
diff --git a/scripts/wan2.1_fun/train_control.py b/scripts/wan2.1_fun/train_control.py
index 378a9ec..fb361c6 100755
--- a/scripts/wan2.1_fun/train_control.py
+++ b/scripts/wan2.1_fun/train_control.py
@@ -63,18 +63,24 @@ for project_root in project_roots:
sys.path.insert(0, project_root) if project_root not in sys.path else None
from videox_fun.data.bucket_sampler import (ASPECT_RATIO_512,
- ASPECT_RATIO_RANDOM_CROP_512,
- ASPECT_RATIO_RANDOM_CROP_PROB,
- AspectRatioBatchImageVideoSampler,
- RandomSampler, get_closest_ratio)
+ ASPECT_RATIO_RANDOM_CROP_512,
+ ASPECT_RATIO_RANDOM_CROP_PROB,
+ AspectRatioBatchImageVideoSampler,
+ RandomSampler, get_closest_ratio)
from videox_fun.data.dataset_image_video import (ImageVideoControlDataset,
- ImageVideoSampler,
- get_random_mask)
+ ImageVideoDataset,
+ ImageVideoSampler,
+ get_random_mask,
+ process_pose_file,
+ process_pose_params)
from videox_fun.models import (AutoencoderKLWan, CLIPModel, WanT5EncoderModel,
WanTransformer3DModel)
from videox_fun.pipeline import WanFunControlPipeline
from videox_fun.utils.discrete_sampler import DiscreteSampling
-from videox_fun.utils.utils import (get_video_to_video_latent,
+from videox_fun.utils.lora_utils import (create_network, merge_lora,
+ unmerge_lora)
+from videox_fun.utils.utils import (get_image_to_video_latent,
+ get_video_to_video_latent,
save_videos_grid)
if is_wandb_available():
@@ -572,7 +578,7 @@ def parse_args():
default="control",
help=(
'The format of training data. Support `"control"`'
- ' (default), `"control_ref"`.'
+ ' (default), `"control_ref"`, `"control_camera_ref"`.'
),
)
parser.add_argument(
@@ -584,6 +590,13 @@ def parse_args():
' (default), `"random"`.'
),
)
+ parser.add_argument(
+ "--add_full_ref_image_in_self_attention",
+ action="store_true",
+ help=(
+ 'Whether enable add full ref image in self attention.'
+ ),
+ )
parser.add_argument(
"--weighting_scheme",
type=str,
@@ -772,7 +785,6 @@ def main():
m, u = transformer3d.load_state_dict(state_dict, strict=False)
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
- assert len(u) == 0
if args.vae_path is not None:
print(f"From checkpoint: {args.vae_path}")
@@ -785,7 +797,6 @@ def main():
m, u = vae.load_state_dict(state_dict, strict=False)
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
- assert len(u) == 0
# A good trainable modules is showed below now.
# For 3D Patch: trainable_modules = ['ff.net', 'pos_embed', 'attn2', 'proj_out', 'timepositionalencoding', 'h_position', 'w_position']
@@ -971,6 +982,7 @@ def main():
video_repeat=args.video_repeat,
image_sample_size=args.image_sample_size,
enable_bucket=args.enable_bucket, enable_inpaint=False,
+ enable_camera_info=args.train_mode == "control_camera_ref"
)
def worker_init_fn(_seed):
@@ -1053,6 +1065,10 @@ def main():
if args.train_mode != "control":
new_examples["ref_pixel_values"] = []
new_examples["clip_pixel_values"] = []
+ new_examples["clip_idx"] = []
+ # Used in Control Camera Ref Mode
+ if args.train_mode == "control_camera_ref":
+ new_examples["control_camera_values"] = []
# Get downsample ratio in image and videos
pixel_value = examples[0]["pixel_values"]
@@ -1069,13 +1085,36 @@ def main():
if args.random_hw_adapt:
if args.training_with_video_token_length:
local_min_size = np.min(np.array([np.mean(np.array([np.shape(example["pixel_values"])[1], np.shape(example["pixel_values"])[2]])) for example in examples]))
- # The video will be resized to a lower resolution than its own.
+
+ def get_random_downsample_probability(choice_list, token_sample_size):
+ length = len(choice_list)
+ if length == 1:
+ return [1.0] # If there's only one element, it gets all the probability
+
+ # Find the index of the closest value to token_sample_size
+ closest_index = min(range(length), key=lambda i: abs(choice_list[i] - token_sample_size))
+
+ # Assign 50% to the closest index
+ first_element = 0.50
+ remaining_sum = 1.0 - first_element
+
+ # Distribute the remaining 50% evenly among the other elements
+ other_elements_value = remaining_sum / (length - 1) if length > 1 else 0.0
+
+ # Construct the probability distribution
+ probability_list = [other_elements_value] * length
+ probability_list[closest_index] = first_element
+
+ return probability_list
+
choice_list = [length for length in list(length_to_frame_num.keys()) if length < local_min_size * 1.25]
if len(choice_list) == 0:
choice_list = list(length_to_frame_num.keys())
- local_video_sample_size = np.random.choice(choice_list)
- batch_video_length = length_to_frame_num[local_video_sample_size]
+ probabilities = get_random_downsample_probability(choice_list, args.token_sample_size)
+ local_video_sample_size = np.random.choice(choice_list, p=probabilities)
+
random_downsample_ratio = args.video_sample_size / local_video_sample_size
+ batch_video_length = length_to_frame_num[local_video_sample_size]
else:
random_downsample_ratio = get_random_downsample_ratio(args.video_sample_size)
batch_video_length = args.video_sample_n_frames + sample_n_frames_bucket_interval
@@ -1119,6 +1158,10 @@ def main():
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
])
+ transform_no_normalize = transforms.Compose([
+ transforms.Resize([nh, nw]),
+ transforms.CenterCrop([int(x) for x in random_sample_size]),
+ ])
else:
# Get adapt hw for resize
closest_size = list(map(lambda x: int(x), closest_size))
@@ -1133,8 +1176,28 @@ def main():
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
])
+ transform_no_normalize = transforms.Compose([
+ transforms.Resize(resize_size, interpolation=transforms.InterpolationMode.BILINEAR), # Image.BICUBIC
+ transforms.CenterCrop(closest_size),
+ ])
+
new_examples["pixel_values"].append(transform(pixel_values))
new_examples["control_pixel_values"].append(transform(control_pixel_values))
+
+ if args.train_mode == "control_camera_ref":
+ control_camera_values = example.get("control_camera_values", None)
+ if control_camera_values is None:
+ control_camera_values_size = (
+ new_examples["control_pixel_values"][-1].size()[0],
+ 6,
+ new_examples["control_pixel_values"][-1].size()[2],
+ new_examples["control_pixel_values"][-1].size()[3]
+ )
+ local_control_camera_values = torch.zeros(control_camera_values_size)
+ new_examples["control_camera_values"].append(local_control_camera_values)
+ else:
+ local_control_camera_values = process_pose_params(example["control_camera_values"], height=resize_size[0], width=resize_size[1]).permute(0, 3, 1, 2).contiguous()
+ new_examples["control_camera_values"].append(transform_no_normalize(local_control_camera_values))
new_examples["text"].append(example["text"])
# Magvae needs the number of frames to be 4n + 1.
@@ -1162,6 +1225,7 @@ def main():
return special_list
number_list_prob = np.array(_create_special_list(len(new_examples["pixel_values"][-1])))
clip_index = np.random.choice(list(range(len(new_examples["pixel_values"][-1]))), p = number_list_prob)
+ new_examples["clip_idx"].append(clip_index)
ref_pixel_values = new_examples["pixel_values"][-1][clip_index].unsqueeze(0)
new_examples["ref_pixel_values"].append(ref_pixel_values)
@@ -1176,6 +1240,9 @@ def main():
if args.train_mode != "control":
new_examples["ref_pixel_values"] = torch.stack([example[:batch_video_length] for example in new_examples["ref_pixel_values"]])
new_examples["clip_pixel_values"] = torch.stack([example for example in new_examples["clip_pixel_values"]])
+ new_examples["clip_idx"] = torch.tensor(new_examples["clip_idx"])
+ if args.train_mode == "control_camera_ref":
+ new_examples["control_camera_values"] = torch.stack([example[:batch_video_length] for example in new_examples["control_camera_values"]])
# Encode prompts when enable_text_encoder_in_dataloader=True
if args.enable_text_encoder_in_dataloader:
@@ -1363,12 +1430,16 @@ def main():
# Convert images to latent space
pixel_values = batch["pixel_values"].to(weight_dtype)
control_pixel_values = batch["control_pixel_values"].to(weight_dtype)
+ if args.train_mode == "control_camera_ref":
+ control_camera_values = batch["control_camera_values"].to(weight_dtype)
# Increase the batch size when the length of the latent sequence of the current sample is small
if args.training_with_video_token_length and zero_stage != 3:
if args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 16 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
pixel_values = torch.tile(pixel_values, (4, 1, 1, 1, 1))
control_pixel_values = torch.tile(control_pixel_values, (4, 1, 1, 1, 1))
+ if args.train_mode == "control_camera_ref":
+ control_camera_values = torch.tile(control_camera_values, (4, 1, 1, 1, 1))
if args.enable_text_encoder_in_dataloader:
batch['encoder_hidden_states'] = torch.tile(batch['encoder_hidden_states'], (4, 1, 1))
batch['encoder_attention_mask'] = torch.tile(batch['encoder_attention_mask'], (4, 1))
@@ -1377,6 +1448,8 @@ def main():
elif args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 4 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
pixel_values = torch.tile(pixel_values, (2, 1, 1, 1, 1))
control_pixel_values = torch.tile(control_pixel_values, (2, 1, 1, 1, 1))
+ if args.train_mode == "control_camera_ref":
+ control_camera_values = torch.tile(control_camera_values, (2, 1, 1, 1, 1))
if args.enable_text_encoder_in_dataloader:
batch['encoder_hidden_states'] = torch.tile(batch['encoder_hidden_states'], (2, 1, 1))
batch['encoder_attention_mask'] = torch.tile(batch['encoder_attention_mask'], (2, 1))
@@ -1386,14 +1459,17 @@ def main():
if args.train_mode != "control":
ref_pixel_values = batch["ref_pixel_values"].to(weight_dtype)
clip_pixel_values = batch["clip_pixel_values"]
+ clip_idx = batch["clip_idx"]
# Increase the batch size when the length of the latent sequence of the current sample is small
if args.training_with_video_token_length and zero_stage != 3:
if args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 16 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
clip_pixel_values = torch.tile(clip_pixel_values, (4, 1, 1, 1))
ref_pixel_values = torch.tile(ref_pixel_values, (4, 1, 1, 1, 1))
+ clip_idx = torch.tile(clip_idx, (4,))
elif args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 4 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
clip_pixel_values = torch.tile(clip_pixel_values, (2, 1, 1, 1))
ref_pixel_values = torch.tile(ref_pixel_values, (2, 1, 1, 1, 1))
+ clip_idx = torch.tile(clip_idx, (2,))
if args.random_frame_crop:
def _create_special_list(length):
@@ -1472,19 +1548,36 @@ def main():
else:
latents = _batch_encode_vae(pixel_values)
- control_latents = _batch_encode_vae(control_pixel_values)
- # Make control latents to zero
- for bs_index in range(control_latents.size()[0]):
- if rng is None:
- zero_init_control_latents_conv_in = np.random.choice([0, 1], p = [0.90, 0.10])
- else:
- zero_init_control_latents_conv_in = rng.choice([0, 1], p = [0.90, 0.10])
+ if args.train_mode != "control_camera_ref":
+ control_latents = _batch_encode_vae(control_pixel_values)
+ # Make control latents to zero
+ for bs_index in range(control_latents.size()[0]):
+ if rng is None:
+ zero_init_control_latents_conv_in = np.random.choice([0, 1], p = [0.90, 0.10])
+ else:
+ zero_init_control_latents_conv_in = rng.choice([0, 1], p = [0.90, 0.10])
- if zero_init_control_latents_conv_in:
- control_latents[bs_index] = control_latents[bs_index] * 0
+ if zero_init_control_latents_conv_in:
+ control_latents[bs_index] = control_latents[bs_index] * 0
+ control_camera_latents = None
+ else:
+ control_latents = None
+ control_camera_latents = rearrange(control_camera_values, "b f c h w -> b c f h w")
+ control_camera_latents = torch.concat(
+ [
+ torch.repeat_interleave(control_camera_latents[:, :, 0:1], repeats=4, dim=2),
+ control_camera_latents[:, :, 1:]
+ ], dim=2
+ ).transpose(1, 2).contiguous()
+ control_camera_latents = control_camera_latents.view(control_camera_latents.shape[0], control_camera_latents.shape[1] // 4, 4, control_camera_latents.shape[2], control_camera_latents.shape[3], control_camera_latents.shape[4])
+ control_camera_latents = control_camera_latents.transpose(2, 3).contiguous()
+ control_camera_latents = control_camera_latents.view(control_camera_latents.shape[0], control_camera_latents.shape[1], control_camera_latents.shape[2] * 4, control_camera_latents.shape[4], control_camera_latents.shape[5])
+ control_camera_latents = control_camera_latents.transpose(1, 2)
if args.train_mode != "control":
ref_latents = _batch_encode_vae(ref_pixel_values)
+ if args.add_full_ref_image_in_self_attention:
+ full_ref = ref_latents[:, :, 0].clone()
ref_latents_conv_in = torch.zeros_like(latents).to(ref_latents.device, ref_latents.dtype)
ref_latents_conv_in[:, :, :1] = ref_latents
@@ -1494,10 +1587,20 @@ def main():
else:
zero_init_ref_latents_conv_in = rng.choice([0, 1], p = [0.90, 0.10])
- if zero_init_ref_latents_conv_in and control_latents.size()[1] != 1:
+ if clip_idx[bs_index] != 0 or (zero_init_ref_latents_conv_in and latents.size()[1] != 1):
ref_latents_conv_in[bs_index, :, :1] = ref_latents_conv_in[bs_index, :, :1] * 0
- control_latents = torch.cat([control_latents, ref_latents_conv_in], dim = 1)
+ if args.add_full_ref_image_in_self_attention:
+ if rng is None:
+ zero_init_full_ref_conv_in = np.random.choice([0, 1], p = [0.90, 0.10])
+ else:
+ zero_init_full_ref_conv_in = rng.choice([0, 1], p = [0.90, 0.10])
+ if clip_idx[bs_index] == 0 or zero_init_full_ref_conv_in:
+ full_ref[bs_index] = full_ref[bs_index] * 0
+ if control_latents is None:
+ control_latents = ref_latents_conv_in
+ else:
+ control_latents = torch.cat([control_latents, ref_latents_conv_in], dim = 1)
clip_context = []
for clip_pixel_value in clip_pixel_values:
@@ -1601,8 +1704,10 @@ def main():
context=prompt_embeds,
t=timesteps,
seq_len=seq_len,
- y=control_latents if args.train_mode != "normal" else None,
- clip_fea=clip_context if args.train_mode != "normal" else None,
+ y=control_latents if args.train_mode != "control" else None,
+ y_camera=control_camera_latents if args.train_mode == "control_camera_ref" else None,
+ clip_fea=clip_context if args.train_mode != "control" else None,
+ full_ref=full_ref if args.add_full_ref_image_in_self_attention else None,
)
def custom_mse_loss(noise_pred, target, weighting=None, threshold=50):
diff --git a/scripts/wan2.1_fun/train_control_lora.py b/scripts/wan2.1_fun/train_control_lora.py
old mode 100644
new mode 100755
index 2dc56d5..cf2484e
--- a/scripts/wan2.1_fun/train_control_lora.py
+++ b/scripts/wan2.1_fun/train_control_lora.py
@@ -70,7 +70,9 @@ from videox_fun.data.bucket_sampler import (ASPECT_RATIO_512,
from videox_fun.data.dataset_image_video import (ImageVideoControlDataset,
ImageVideoDataset,
ImageVideoSampler,
- get_random_mask)
+ get_random_mask,
+ process_pose_file,
+ process_pose_params)
from videox_fun.models import (AutoencoderKLWan, CLIPModel, WanT5EncoderModel,
WanTransformer3DModel)
from videox_fun.pipeline import WanFunControlPipeline
@@ -568,7 +570,7 @@ def parse_args():
default="control",
help=(
'The format of training data. Support `"control"`'
- ' (default), `"control_ref"`.'
+ ' (default), `"control_ref"`, `"control_camera_ref"`.'
),
)
parser.add_argument(
@@ -580,6 +582,13 @@ def parse_args():
' (default), `"random"`.'
),
)
+ parser.add_argument(
+ "--add_full_ref_image_in_self_attention",
+ action="store_true",
+ help=(
+ 'Whether enable add full ref image in self attention.'
+ ),
+ )
parser.add_argument(
"--weighting_scheme",
type=str,
@@ -792,7 +801,6 @@ def main():
m, u = transformer3d.load_state_dict(state_dict, strict=False)
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
- assert len(u) == 0
if args.vae_path is not None:
print(f"From checkpoint: {args.vae_path}")
@@ -805,7 +813,6 @@ def main():
m, u = vae.load_state_dict(state_dict, strict=False)
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
- assert len(u) == 0
# `accelerate` 0.16.0 will have better support for customized saving
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
@@ -913,6 +920,7 @@ def main():
video_repeat=args.video_repeat,
image_sample_size=args.image_sample_size,
enable_bucket=args.enable_bucket, enable_inpaint=False,
+ enable_camera_info=args.train_mode == "control_camera_ref"
)
def worker_init_fn(_seed):
@@ -995,6 +1003,10 @@ def main():
if args.train_mode != "control":
new_examples["ref_pixel_values"] = []
new_examples["clip_pixel_values"] = []
+ new_examples["clip_idx"] = []
+ # Used in Control Camera Ref Mode
+ if args.train_mode == "control_camera_ref":
+ new_examples["control_camera_values"] = []
# Get downsample ratio in image and videos
pixel_value = examples[0]["pixel_values"]
@@ -1011,13 +1023,36 @@ def main():
if args.random_hw_adapt:
if args.training_with_video_token_length:
local_min_size = np.min(np.array([np.mean(np.array([np.shape(example["pixel_values"])[1], np.shape(example["pixel_values"])[2]])) for example in examples]))
- # The video will be resized to a lower resolution than its own.
+
+ def get_random_downsample_probability(choice_list, token_sample_size):
+ length = len(choice_list)
+ if length == 1:
+ return [1.0] # If there's only one element, it gets all the probability
+
+ # Find the index of the closest value to token_sample_size
+ closest_index = min(range(length), key=lambda i: abs(choice_list[i] - token_sample_size))
+
+ # Assign 50% to the closest index
+ first_element = 0.50
+ remaining_sum = 1.0 - first_element
+
+ # Distribute the remaining 50% evenly among the other elements
+ other_elements_value = remaining_sum / (length - 1) if length > 1 else 0.0
+
+ # Construct the probability distribution
+ probability_list = [other_elements_value] * length
+ probability_list[closest_index] = first_element
+
+ return probability_list
+
choice_list = [length for length in list(length_to_frame_num.keys()) if length < local_min_size * 1.25]
if len(choice_list) == 0:
choice_list = list(length_to_frame_num.keys())
- local_video_sample_size = np.random.choice(choice_list)
- batch_video_length = length_to_frame_num[local_video_sample_size]
+ probabilities = get_random_downsample_probability(choice_list, args.token_sample_size)
+ local_video_sample_size = np.random.choice(choice_list, p=probabilities)
+
random_downsample_ratio = args.video_sample_size / local_video_sample_size
+ batch_video_length = length_to_frame_num[local_video_sample_size]
else:
random_downsample_ratio = get_random_downsample_ratio(args.video_sample_size)
batch_video_length = args.video_sample_n_frames + sample_n_frames_bucket_interval
@@ -1061,6 +1096,10 @@ def main():
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
])
+ transform_no_normalize = transforms.Compose([
+ transforms.Resize([nh, nw]),
+ transforms.CenterCrop([int(x) for x in random_sample_size]),
+ ])
else:
# Get adapt hw for resize
closest_size = list(map(lambda x: int(x), closest_size))
@@ -1075,8 +1114,28 @@ def main():
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
])
+ transform_no_normalize = transforms.Compose([
+ transforms.Resize(resize_size, interpolation=transforms.InterpolationMode.BILINEAR), # Image.BICUBIC
+ transforms.CenterCrop(closest_size),
+ ])
+
new_examples["pixel_values"].append(transform(pixel_values))
new_examples["control_pixel_values"].append(transform(control_pixel_values))
+
+ if args.train_mode == "control_camera_ref":
+ control_camera_values = example.get("control_camera_values", None)
+ if control_camera_values is None:
+ control_camera_values_size = (
+ new_examples["control_pixel_values"][-1].size()[0],
+ 6,
+ new_examples["control_pixel_values"][-1].size()[2],
+ new_examples["control_pixel_values"][-1].size()[3]
+ )
+ local_control_camera_values = torch.zeros(control_camera_values_size)
+ new_examples["control_camera_values"].append(local_control_camera_values)
+ else:
+ local_control_camera_values = process_pose_params(example["control_camera_values"], height=resize_size[0], width=resize_size[1]).permute(0, 3, 1, 2).contiguous()
+ new_examples["control_camera_values"].append(transform_no_normalize(local_control_camera_values))
new_examples["text"].append(example["text"])
# Magvae needs the number of frames to be 4n + 1.
@@ -1104,6 +1163,7 @@ def main():
return special_list
number_list_prob = np.array(_create_special_list(len(new_examples["pixel_values"][-1])))
clip_index = np.random.choice(list(range(len(new_examples["pixel_values"][-1]))), p = number_list_prob)
+ new_examples["clip_idx"].append(clip_index)
ref_pixel_values = new_examples["pixel_values"][-1][clip_index].unsqueeze(0)
new_examples["ref_pixel_values"].append(ref_pixel_values)
@@ -1118,6 +1178,9 @@ def main():
if args.train_mode != "control":
new_examples["ref_pixel_values"] = torch.stack([example[:batch_video_length] for example in new_examples["ref_pixel_values"]])
new_examples["clip_pixel_values"] = torch.stack([example for example in new_examples["clip_pixel_values"]])
+ new_examples["clip_idx"] = torch.tensor(new_examples["clip_idx"])
+ if args.train_mode == "control_camera_ref":
+ new_examples["control_camera_values"] = torch.stack([example[:batch_video_length] for example in new_examples["control_camera_values"]])
# Encode prompts when enable_text_encoder_in_dataloader=True
if args.enable_text_encoder_in_dataloader:
@@ -1315,12 +1378,16 @@ def main():
# Convert images to latent space
pixel_values = batch["pixel_values"].to(weight_dtype)
control_pixel_values = batch["control_pixel_values"].to(weight_dtype)
+ if args.train_mode == "control_camera_ref":
+ control_camera_values = batch["control_camera_values"].to(weight_dtype)
# Increase the batch size when the length of the latent sequence of the current sample is small
if args.training_with_video_token_length and zero_stage != 3:
if args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 16 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
pixel_values = torch.tile(pixel_values, (4, 1, 1, 1, 1))
control_pixel_values = torch.tile(control_pixel_values, (4, 1, 1, 1, 1))
+ if args.train_mode == "control_camera_ref":
+ control_camera_values = torch.tile(control_camera_values, (4, 1, 1, 1, 1))
if args.enable_text_encoder_in_dataloader:
batch['encoder_hidden_states'] = torch.tile(batch['encoder_hidden_states'], (4, 1, 1))
batch['encoder_attention_mask'] = torch.tile(batch['encoder_attention_mask'], (4, 1))
@@ -1329,6 +1396,8 @@ def main():
elif args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 4 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
pixel_values = torch.tile(pixel_values, (2, 1, 1, 1, 1))
control_pixel_values = torch.tile(control_pixel_values, (2, 1, 1, 1, 1))
+ if args.train_mode == "control_camera_ref":
+ control_camera_values = torch.tile(control_camera_values, (2, 1, 1, 1, 1))
if args.enable_text_encoder_in_dataloader:
batch['encoder_hidden_states'] = torch.tile(batch['encoder_hidden_states'], (2, 1, 1))
batch['encoder_attention_mask'] = torch.tile(batch['encoder_attention_mask'], (2, 1))
@@ -1338,14 +1407,17 @@ def main():
if args.train_mode != "control":
ref_pixel_values = batch["ref_pixel_values"].to(weight_dtype)
clip_pixel_values = batch["clip_pixel_values"]
+ clip_idx = batch["clip_idx"]
# Increase the batch size when the length of the latent sequence of the current sample is small
if args.training_with_video_token_length and zero_stage != 3:
if args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 16 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
clip_pixel_values = torch.tile(clip_pixel_values, (4, 1, 1, 1))
ref_pixel_values = torch.tile(ref_pixel_values, (4, 1, 1, 1, 1))
+ clip_idx = torch.tile(clip_idx, (4,))
elif args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 4 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
clip_pixel_values = torch.tile(clip_pixel_values, (2, 1, 1, 1))
ref_pixel_values = torch.tile(ref_pixel_values, (2, 1, 1, 1, 1))
+ clip_idx = torch.tile(clip_idx, (2,))
if args.random_frame_crop:
def _create_special_list(length):
@@ -1424,19 +1496,36 @@ def main():
else:
latents = _batch_encode_vae(pixel_values)
- control_latents = _batch_encode_vae(control_pixel_values)
- # Make control latents to zero
- for bs_index in range(control_latents.size()[0]):
- if rng is None:
- zero_init_control_latents_conv_in = np.random.choice([0, 1], p = [0.90, 0.10])
- else:
- zero_init_control_latents_conv_in = rng.choice([0, 1], p = [0.90, 0.10])
+ if args.train_mode != "control_camera_ref":
+ control_latents = _batch_encode_vae(control_pixel_values)
+ # Make control latents to zero
+ for bs_index in range(control_latents.size()[0]):
+ if rng is None:
+ zero_init_control_latents_conv_in = np.random.choice([0, 1], p = [0.90, 0.10])
+ else:
+ zero_init_control_latents_conv_in = rng.choice([0, 1], p = [0.90, 0.10])
- if zero_init_control_latents_conv_in:
- control_latents[bs_index] = control_latents[bs_index] * 0
+ if zero_init_control_latents_conv_in:
+ control_latents[bs_index] = control_latents[bs_index] * 0
+ control_camera_latents = None
+ else:
+ control_latents = None
+ control_camera_latents = rearrange(control_camera_values, "b f c h w -> b c f h w")
+ control_camera_latents = torch.concat(
+ [
+ torch.repeat_interleave(control_camera_latents[:, :, 0:1], repeats=4, dim=2),
+ control_camera_latents[:, :, 1:]
+ ], dim=2
+ ).transpose(1, 2).contiguous()
+ control_camera_latents = control_camera_latents.view(control_camera_latents.shape[0], control_camera_latents.shape[1] // 4, 4, control_camera_latents.shape[2], control_camera_latents.shape[3], control_camera_latents.shape[4])
+ control_camera_latents = control_camera_latents.transpose(2, 3).contiguous()
+ control_camera_latents = control_camera_latents.view(control_camera_latents.shape[0], control_camera_latents.shape[1], control_camera_latents.shape[2] * 4, control_camera_latents.shape[4], control_camera_latents.shape[5])
+ control_camera_latents = control_camera_latents.transpose(1, 2)
if args.train_mode != "control":
ref_latents = _batch_encode_vae(ref_pixel_values)
+ if args.add_full_ref_image_in_self_attention:
+ full_ref = ref_latents[:, :, 0].clone()
ref_latents_conv_in = torch.zeros_like(latents).to(ref_latents.device, ref_latents.dtype)
ref_latents_conv_in[:, :, :1] = ref_latents
@@ -1446,10 +1535,20 @@ def main():
else:
zero_init_ref_latents_conv_in = rng.choice([0, 1], p = [0.90, 0.10])
- if zero_init_ref_latents_conv_in and control_latents.size()[1] != 1:
+ if clip_idx[bs_index] != 0 or (zero_init_ref_latents_conv_in and latents.size()[1] != 1):
ref_latents_conv_in[bs_index, :, :1] = ref_latents_conv_in[bs_index, :, :1] * 0
- control_latents = torch.cat([control_latents, ref_latents_conv_in], dim = 1)
+ if args.add_full_ref_image_in_self_attention:
+ if rng is None:
+ zero_init_full_ref_conv_in = np.random.choice([0, 1], p = [0.90, 0.10])
+ else:
+ zero_init_full_ref_conv_in = rng.choice([0, 1], p = [0.90, 0.10])
+ if clip_idx[bs_index] == 0 or zero_init_full_ref_conv_in:
+ full_ref[bs_index] = full_ref[bs_index] * 0
+ if control_latents is None:
+ control_latents = ref_latents_conv_in
+ else:
+ control_latents = torch.cat([control_latents, ref_latents_conv_in], dim = 1)
clip_context = []
for clip_pixel_value in clip_pixel_values:
@@ -1553,8 +1652,10 @@ def main():
context=prompt_embeds,
t=timesteps,
seq_len=seq_len,
- y=control_latents if args.train_mode != "normal" else None,
- clip_fea=clip_context if args.train_mode != "normal" else None,
+ y=control_latents if args.train_mode != "control" else None,
+ y_camera=control_camera_latents if args.train_mode == "control_camera_ref" else None,
+ clip_fea=clip_context if args.train_mode != "control" else None,
+ full_ref=full_ref if args.add_full_ref_image_in_self_attention else None,
)
def custom_mse_loss(noise_pred, target, weighting=None, threshold=50):
diff --git a/videox_fun/data/dataset_image_video.py b/videox_fun/data/dataset_image_video.py
old mode 100644
new mode 100755
index 0288432..e1ef788
--- a/videox_fun/data/dataset_image_video.py
+++ b/videox_fun/data/dataset_image_video.py
@@ -1,24 +1,27 @@
import csv
+import gc
import io
import json
import math
import os
import random
+from contextlib import contextmanager
+from random import shuffle
from threading import Thread
import albumentations
import cv2
-import gc
import numpy as np
import torch
+import torch.nn.functional as F
import torchvision.transforms as transforms
-
-from func_timeout import func_timeout, FunctionTimedOut
from decord import VideoReader
+from einops import rearrange
+from func_timeout import FunctionTimedOut, func_timeout
+from packaging import version as pver
from PIL import Image
from torch.utils.data import BatchSampler, Sampler
from torch.utils.data.dataset import Dataset
-from contextlib import contextmanager
VIDEO_READER_TIMEOUT = 20
@@ -107,6 +110,152 @@ def get_random_mask(shape, image_start_only=False):
mask[:, :, :, :] = 1
return mask
+class Camera(object):
+ """Copied from https://github.com/hehao13/CameraCtrl/blob/main/inference.py
+ """
+ def __init__(self, entry):
+ fx, fy, cx, cy = entry[1:5]
+ self.fx = fx
+ self.fy = fy
+ self.cx = cx
+ self.cy = cy
+ w2c_mat = np.array(entry[7:]).reshape(3, 4)
+ w2c_mat_4x4 = np.eye(4)
+ w2c_mat_4x4[:3, :] = w2c_mat
+ self.w2c_mat = w2c_mat_4x4
+ self.c2w_mat = np.linalg.inv(w2c_mat_4x4)
+
+def custom_meshgrid(*args):
+ """Copied from https://github.com/hehao13/CameraCtrl/blob/main/inference.py
+ """
+ # ref: https://pytorch.org/docs/stable/generated/torch.meshgrid.html?highlight=meshgrid#torch.meshgrid
+ if pver.parse(torch.__version__) < pver.parse('1.10'):
+ return torch.meshgrid(*args)
+ else:
+ return torch.meshgrid(*args, indexing='ij')
+
+def get_relative_pose(cam_params):
+ """Copied from https://github.com/hehao13/CameraCtrl/blob/main/inference.py
+ """
+ abs_w2cs = [cam_param.w2c_mat for cam_param in cam_params]
+ abs_c2ws = [cam_param.c2w_mat for cam_param in cam_params]
+ cam_to_origin = 0
+ target_cam_c2w = np.array([
+ [1, 0, 0, 0],
+ [0, 1, 0, -cam_to_origin],
+ [0, 0, 1, 0],
+ [0, 0, 0, 1]
+ ])
+ abs2rel = target_cam_c2w @ abs_w2cs[0]
+ ret_poses = [target_cam_c2w, ] + [abs2rel @ abs_c2w for abs_c2w in abs_c2ws[1:]]
+ ret_poses = np.array(ret_poses, dtype=np.float32)
+ return ret_poses
+
+def ray_condition(K, c2w, H, W, device):
+ """Copied from https://github.com/hehao13/CameraCtrl/blob/main/inference.py
+ """
+ # c2w: B, V, 4, 4
+ # K: B, V, 4
+
+ B = K.shape[0]
+
+ j, i = custom_meshgrid(
+ torch.linspace(0, H - 1, H, device=device, dtype=c2w.dtype),
+ torch.linspace(0, W - 1, W, device=device, dtype=c2w.dtype),
+ )
+ i = i.reshape([1, 1, H * W]).expand([B, 1, H * W]) + 0.5 # [B, HxW]
+ j = j.reshape([1, 1, H * W]).expand([B, 1, H * W]) + 0.5 # [B, HxW]
+
+ fx, fy, cx, cy = K.chunk(4, dim=-1) # B,V, 1
+
+ zs = torch.ones_like(i) # [B, HxW]
+ xs = (i - cx) / fx * zs
+ ys = (j - cy) / fy * zs
+ zs = zs.expand_as(ys)
+
+ directions = torch.stack((xs, ys, zs), dim=-1) # B, V, HW, 3
+ directions = directions / directions.norm(dim=-1, keepdim=True) # B, V, HW, 3
+
+ rays_d = directions @ c2w[..., :3, :3].transpose(-1, -2) # B, V, 3, HW
+ rays_o = c2w[..., :3, 3] # B, V, 3
+ rays_o = rays_o[:, :, None].expand_as(rays_d) # B, V, 3, HW
+ # c2w @ dirctions
+ rays_dxo = torch.cross(rays_o, rays_d)
+ plucker = torch.cat([rays_dxo, rays_d], dim=-1)
+ plucker = plucker.reshape(B, c2w.shape[1], H, W, 6) # B, V, H, W, 6
+ # plucker = plucker.permute(0, 1, 4, 2, 3)
+ return plucker
+
+def process_pose_file(pose_file_path, width=672, height=384, original_pose_width=1280, original_pose_height=720, device='cpu', return_poses=False):
+ """Modified from https://github.com/hehao13/CameraCtrl/blob/main/inference.py
+ """
+ with open(pose_file_path, 'r') as f:
+ poses = f.readlines()
+
+ poses = [pose.strip().split(' ') for pose in poses[1:]]
+ cam_params = [[float(x) for x in pose] for pose in poses]
+ if return_poses:
+ return cam_params
+ else:
+ cam_params = [Camera(cam_param) for cam_param in cam_params]
+
+ sample_wh_ratio = width / height
+ pose_wh_ratio = original_pose_width / original_pose_height # Assuming placeholder ratios, change as needed
+
+ if pose_wh_ratio > sample_wh_ratio:
+ resized_ori_w = height * pose_wh_ratio
+ for cam_param in cam_params:
+ cam_param.fx = resized_ori_w * cam_param.fx / width
+ else:
+ resized_ori_h = width / pose_wh_ratio
+ for cam_param in cam_params:
+ cam_param.fy = resized_ori_h * cam_param.fy / height
+
+ intrinsic = np.asarray([[cam_param.fx * width,
+ cam_param.fy * height,
+ cam_param.cx * width,
+ cam_param.cy * height]
+ for cam_param in cam_params], dtype=np.float32)
+
+ K = torch.as_tensor(intrinsic)[None] # [1, 1, 4]
+ c2ws = get_relative_pose(cam_params) # Assuming this function is defined elsewhere
+ c2ws = torch.as_tensor(c2ws)[None] # [1, n_frame, 4, 4]
+ plucker_embedding = ray_condition(K, c2ws, height, width, device=device)[0].permute(0, 3, 1, 2).contiguous() # V, 6, H, W
+ plucker_embedding = plucker_embedding[None]
+ plucker_embedding = rearrange(plucker_embedding, "b f c h w -> b f h w c")[0]
+ return plucker_embedding
+
+def process_pose_params(cam_params, width=672, height=384, original_pose_width=1280, original_pose_height=720, device='cpu'):
+ """Modified from https://github.com/hehao13/CameraCtrl/blob/main/inference.py
+ """
+ cam_params = [Camera(cam_param) for cam_param in cam_params]
+
+ sample_wh_ratio = width / height
+ pose_wh_ratio = original_pose_width / original_pose_height # Assuming placeholder ratios, change as needed
+
+ if pose_wh_ratio > sample_wh_ratio:
+ resized_ori_w = height * pose_wh_ratio
+ for cam_param in cam_params:
+ cam_param.fx = resized_ori_w * cam_param.fx / width
+ else:
+ resized_ori_h = width / pose_wh_ratio
+ for cam_param in cam_params:
+ cam_param.fy = resized_ori_h * cam_param.fy / height
+
+ intrinsic = np.asarray([[cam_param.fx * width,
+ cam_param.fy * height,
+ cam_param.cx * width,
+ cam_param.cy * height]
+ for cam_param in cam_params], dtype=np.float32)
+
+ K = torch.as_tensor(intrinsic)[None] # [1, 1, 4]
+ c2ws = get_relative_pose(cam_params) # Assuming this function is defined elsewhere
+ c2ws = torch.as_tensor(c2ws)[None] # [1, n_frame, 4, 4]
+ plucker_embedding = ray_condition(K, c2ws, height, width, device=device)[0].permute(0, 3, 1, 2).contiguous() # V, 6, H, W
+ plucker_embedding = plucker_embedding[None]
+ plucker_embedding = rearrange(plucker_embedding, "b f c h w -> b f h w c")[0]
+ return plucker_embedding
+
class ImageVideoSampler(BatchSampler):
"""A sampler wrapper for grouping images with similar aspect ratio into a same batch.
@@ -361,19 +510,19 @@ class ImageVideoDataset(Dataset):
return sample
-
class ImageVideoControlDataset(Dataset):
def __init__(
- self,
- ann_path, data_root=None,
- video_sample_size=512, video_sample_stride=4, video_sample_n_frames=16,
- image_sample_size=512,
- video_repeat=0,
- text_drop_ratio=0.1,
- enable_bucket=False,
- video_length_drop_start=0.0,
- video_length_drop_end=1.0,
- enable_inpaint=False,
+ self,
+ ann_path, data_root=None,
+ video_sample_size=512, video_sample_stride=4, video_sample_n_frames=16,
+ image_sample_size=512,
+ video_repeat=0,
+ text_drop_ratio=0.1,
+ enable_bucket=False,
+ video_length_drop_start=0.1,
+ video_length_drop_end=0.9,
+ enable_inpaint=False,
+ enable_camera_info=False,
):
# Loading annotations from files
print(f"loading annotations from {ann_path} ...")
@@ -403,6 +552,7 @@ class ImageVideoControlDataset(Dataset):
self.enable_bucket = enable_bucket
self.text_drop_ratio = text_drop_ratio
self.enable_inpaint = enable_inpaint
+ self.enable_camera_info = enable_camera_info
self.video_length_drop_start = video_length_drop_start
self.video_length_drop_end = video_length_drop_end
@@ -418,6 +568,13 @@ class ImageVideoControlDataset(Dataset):
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
]
)
+ if self.enable_camera_info:
+ self.video_transforms_camera = transforms.Compose(
+ [
+ transforms.Resize(min(self.video_sample_size)),
+ transforms.CenterCrop(self.video_sample_size)
+ ]
+ )
# Image params
self.image_sample_size = tuple(image_sample_size) if not isinstance(image_sample_size, int) else (image_sample_size, image_sample_size)
@@ -490,33 +647,59 @@ class ImageVideoControlDataset(Dataset):
else:
control_video_id = os.path.join(self.data_root, control_video_id)
- with VideoReader_contextmanager(control_video_id, num_threads=2) as control_video_reader:
- try:
- sample_args = (control_video_reader, batch_index)
- control_pixel_values = func_timeout(
- VIDEO_READER_TIMEOUT, get_video_reader_batch, args=sample_args
- )
- resized_frames = []
- for i in range(len(control_pixel_values)):
- frame = control_pixel_values[i]
- resized_frame = resize_frame(frame, self.larger_side_of_image_and_video)
- resized_frames.append(resized_frame)
- control_pixel_values = np.array(resized_frames)
- except FunctionTimedOut:
- raise ValueError(f"Read {idx} timeout.")
- except Exception as e:
- raise ValueError(f"Failed to extract frames from video. Error is {e}.")
+ if self.enable_camera_info:
+ if control_video_id.lower().endswith('.txt'):
+ if not self.enable_bucket:
+ control_pixel_values = torch.zeros_like(pixel_values)
- if not self.enable_bucket:
- control_pixel_values = torch.from_numpy(control_pixel_values).permute(0, 3, 1, 2).contiguous()
- control_pixel_values = control_pixel_values / 255.
- del control_video_reader
+ control_camera_values = process_pose_file(control_video_id, width=self.video_sample_size[1], height=self.video_sample_size[0])
+ control_camera_values = torch.from_numpy(control_camera_values).permute(0, 3, 1, 2).contiguous()
+ control_camera_values = F.interpolate(control_camera_values, size=(len(video_reader), control_camera_values.size(3)), mode='bilinear', align_corners=True)
+ control_camera_values = self.video_transforms_camera(control_camera_values)
+ else:
+ control_pixel_values = np.zeros_like(pixel_values)
+
+ control_camera_values = process_pose_file(control_video_id, width=self.video_sample_size[1], height=self.video_sample_size[0], return_poses=True)
+ control_camera_values = torch.from_numpy(np.array(control_camera_values)).unsqueeze(0).unsqueeze(0)
+ control_camera_values = F.interpolate(control_camera_values, size=(len(video_reader), control_camera_values.size(3)), mode='bilinear', align_corners=True)[0][0]
+ control_camera_values = np.array([control_camera_values[index] for index in batch_index])
else:
- control_pixel_values = control_pixel_values
+ if not self.enable_bucket:
+ control_pixel_values = torch.zeros_like(pixel_values)
+ control_camera_values = None
+ else:
+ control_pixel_values = np.zeros_like(pixel_values)
+ control_camera_values = None
+ else:
+ with VideoReader_contextmanager(control_video_id, num_threads=2) as control_video_reader:
+ try:
+ sample_args = (control_video_reader, batch_index)
+ control_pixel_values = func_timeout(
+ VIDEO_READER_TIMEOUT, get_video_reader_batch, args=sample_args
+ )
+ resized_frames = []
+ for i in range(len(control_pixel_values)):
+ frame = control_pixel_values[i]
+ resized_frame = resize_frame(frame, self.larger_side_of_image_and_video)
+ resized_frames.append(resized_frame)
+ control_pixel_values = np.array(resized_frames)
+ except FunctionTimedOut:
+ raise ValueError(f"Read {idx} timeout.")
+ except Exception as e:
+ raise ValueError(f"Failed to extract frames from video. Error is {e}.")
- if not self.enable_bucket:
- control_pixel_values = self.video_transforms(control_pixel_values)
- return pixel_values, control_pixel_values, text, "video"
+ if not self.enable_bucket:
+ control_pixel_values = torch.from_numpy(control_pixel_values).permute(0, 3, 1, 2).contiguous()
+ control_pixel_values = control_pixel_values / 255.
+ del control_video_reader
+ else:
+ control_pixel_values = control_pixel_values
+
+ if not self.enable_bucket:
+ control_pixel_values = self.video_transforms(control_pixel_values)
+ control_camera_values = None
+
+ return pixel_values, control_pixel_values, control_camera_values, text, "video"
else:
image_path, text = data_info['file_path'], data_info['text']
if self.data_root is not None:
@@ -542,8 +725,7 @@ class ImageVideoControlDataset(Dataset):
control_image = self.image_transforms(control_image).unsqueeze(0)
else:
control_image = np.expand_dims(np.array(control_image), 0)
- return image, control_image, text, 'image'
-
+ return image, control_image, None, text, 'image'
def __len__(self):
return self.length
@@ -558,13 +740,17 @@ class ImageVideoControlDataset(Dataset):
if data_type_local != data_type:
raise ValueError("data_type_local != data_type")
- pixel_values, control_pixel_values, name, data_type = self.get_batch(idx)
+ pixel_values, control_pixel_values, control_camera_values, name, data_type = self.get_batch(idx)
+
sample["pixel_values"] = pixel_values
sample["control_pixel_values"] = control_pixel_values
sample["text"] = name
sample["data_type"] = data_type
sample["idx"] = idx
-
+
+ if self.enable_camera_info:
+ sample["control_camera_values"] = control_camera_values
+
if len(sample) > 0:
break
except Exception as e:
diff --git a/videox_fun/dist/__init__.py b/videox_fun/dist/__init__.py
index a628f16..31f1827 100755
--- a/videox_fun/dist/__init__.py
+++ b/videox_fun/dist/__init__.py
@@ -1,14 +1,25 @@
import torch
import torch.distributed as dist
+from .fsdp import shard_model
+
try:
- import xfuser
- from xfuser.core.distributed import (get_sequence_parallel_rank,
- get_sequence_parallel_world_size,
- get_sp_group, get_world_group,
- init_distributed_environment,
- initialize_model_parallel)
- from xfuser.core.long_ctx_attention import xFuserLongContextAttention
+ try:
+ import pai_fuser
+ from pai_fuser.core.distributed import (
+ get_sequence_parallel_rank, get_sequence_parallel_world_size,
+ get_sp_group, get_world_group, init_distributed_environment,
+ initialize_model_parallel)
+ from pai_fuser.core.long_ctx_attention import \
+ xFuserLongContextAttention
+ except Exception as ex:
+ import xfuser
+ from xfuser.core.distributed import (get_sequence_parallel_rank,
+ get_sequence_parallel_world_size,
+ get_sp_group, get_world_group,
+ init_distributed_environment,
+ initialize_model_parallel)
+ from xfuser.core.long_ctx_attention import xFuserLongContextAttention
except Exception as ex:
get_sequence_parallel_world_size = None
get_sequence_parallel_rank = None
@@ -18,6 +29,17 @@ except Exception as ex:
init_distributed_environment = None
initialize_model_parallel = None
+try:
+ from pai_fuser.core import parallel_magvit_vae
+except:
+ def parallel_magvit_vae(multi_gpus_overlap_scale, spatial_compression_ratio):
+ def decorator(func):
+ def wrapper(self, z, *args, **kwargs):
+ decoded = func(self, z, *args, **kwargs)
+ return decoded
+ return wrapper
+ return decorator
+
def set_multi_gpus_devices(ulysses_degree, ring_degree):
if ulysses_degree > 1 or ring_degree > 1:
if get_sp_group is None:
diff --git a/videox_fun/dist/cogvideox_xfuser.py b/videox_fun/dist/cogvideox_xfuser.py
old mode 100644
new mode 100755
index 55b838d..7b29cb7
--- a/videox_fun/dist/cogvideox_xfuser.py
+++ b/videox_fun/dist/cogvideox_xfuser.py
@@ -5,21 +5,10 @@ import torch.nn.functional as F
from diffusers.models.attention import Attention
from diffusers.models.embeddings import apply_rotary_emb
-try:
- import xfuser
- from xfuser.core.distributed import (get_sequence_parallel_rank,
- get_sequence_parallel_world_size,
- get_sp_group,
- init_distributed_environment,
- initialize_model_parallel)
- from xfuser.core.long_ctx_attention import xFuserLongContextAttention
-except Exception as ex:
- get_sequence_parallel_world_size = None
- get_sequence_parallel_rank = None
- xFuserLongContextAttention = None
- get_sp_group = None
- init_distributed_environment = None
- initialize_model_parallel = None
+from ..dist import (get_sequence_parallel_rank,
+ get_sequence_parallel_world_size, get_sp_group,
+ init_distributed_environment, initialize_model_parallel,
+ xFuserLongContextAttention)
class CogVideoXMultiGPUsAttnProcessor2_0:
r"""
diff --git a/videox_fun/dist/fsdp.py b/videox_fun/dist/fsdp.py
new file mode 100644
index 0000000..569621a
--- /dev/null
+++ b/videox_fun/dist/fsdp.py
@@ -0,0 +1,42 @@
+# Copyied from https://github.com/Wan-Video/Wan2.1/blob/main/wan/distributed/fsdp.py
+# Copyright 2024-2025 The Alibaba Wan Team Authors. All rights reserved.
+import gc
+from functools import partial
+
+import torch
+from torch.distributed.fsdp import FullyShardedDataParallel as FSDP
+from torch.distributed.fsdp import MixedPrecision, ShardingStrategy
+from torch.distributed.fsdp.wrap import lambda_auto_wrap_policy
+from torch.distributed.utils import _free_storage
+
+def shard_model(
+ model,
+ device_id,
+ param_dtype=torch.bfloat16,
+ reduce_dtype=torch.float32,
+ buffer_dtype=torch.float32,
+ process_group=None,
+ sharding_strategy=ShardingStrategy.FULL_SHARD,
+ sync_module_states=True,
+):
+ model = FSDP(
+ module=model,
+ process_group=process_group,
+ sharding_strategy=sharding_strategy,
+ auto_wrap_policy=partial(
+ lambda_auto_wrap_policy, lambda_fn=lambda m: m in model.blocks),
+ mixed_precision=MixedPrecision(
+ param_dtype=param_dtype,
+ reduce_dtype=reduce_dtype,
+ buffer_dtype=buffer_dtype),
+ device_id=device_id,
+ sync_module_states=sync_module_states)
+ return model
+
+def free_model(model):
+ for m in model.modules():
+ if isinstance(m, FSDP):
+ _free_storage(m._handle.flat_param.data)
+ del model
+ gc.collect()
+ torch.cuda.empty_cache()
\ No newline at end of file
diff --git a/videox_fun/dist/wan_xfuser.py b/videox_fun/dist/wan_xfuser.py
old mode 100644
new mode 100755
index 949983d..f80a9d8
--- a/videox_fun/dist/wan_xfuser.py
+++ b/videox_fun/dist/wan_xfuser.py
@@ -1,21 +1,11 @@
import torch
import torch.cuda.amp as amp
-try:
- import xfuser
- from xfuser.core.distributed import (get_sequence_parallel_rank,
- get_sequence_parallel_world_size,
- get_sp_group,
- init_distributed_environment,
- initialize_model_parallel)
- from xfuser.core.long_ctx_attention import xFuserLongContextAttention
-except Exception as ex:
- get_sequence_parallel_world_size = None
- get_sequence_parallel_rank = None
- xFuserLongContextAttention = None
- get_sp_group = None
- init_distributed_environment = None
- initialize_model_parallel = None
+from ..dist import (get_sequence_parallel_rank,
+ get_sequence_parallel_world_size, get_sp_group,
+ init_distributed_environment, initialize_model_parallel,
+ xFuserLongContextAttention)
+
def pad_freqs(original_tensor, target_len):
seq_len, s1, s2 = original_tensor.shape
diff --git a/videox_fun/models/cache_utils.py b/videox_fun/models/cache_utils.py
old mode 100644
new mode 100755
index 871b10c..117e9fc
--- a/videox_fun/models/cache_utils.py
+++ b/videox_fun/models/cache_utils.py
@@ -3,9 +3,9 @@ import torch
def get_teacache_coefficients(model_name):
- if "wan2.1-t2v-1.3b" in model_name.lower() or "wan2.1-fun-1.3b" in model_name.lower():
+ if "wan2.1-t2v-1.3b" in model_name.lower() or "wan2.1-fun-1.3b" in model_name.lower() or "wan2.1-fun-v1.1-1.3b" in model_name.lower():
return [-5.21862437e+04, 9.23041404e+03, -5.28275948e+02, 1.36987616e+01, -4.99875664e-02]
- elif "wan2.1-t2v-14b" in model_name.lower():
+ elif "wan2.1-t2v-14b" in model_name.lower() or "wan2.1-fun-v1.1-14b" in model_name.lower():
return [-3.03318725e+05, 4.90537029e+04, -2.65530556e+03, 5.87365115e+01, -3.15583525e-01]
elif "wan2.1-i2v-14b-480p" in model_name.lower():
return [2.57151496e+05, -3.54229917e+04, 1.40286849e+03, -1.35890334e+01, 1.32517977e-01]
diff --git a/videox_fun/models/wan_camera_adapter.py b/videox_fun/models/wan_camera_adapter.py
new file mode 100644
index 0000000..a22c1a9
--- /dev/null
+++ b/videox_fun/models/wan_camera_adapter.py
@@ -0,0 +1,62 @@
+import torch
+import torch.nn as nn
+
+class SimpleAdapter(nn.Module):
+ def __init__(self, in_dim, out_dim, kernel_size, stride, num_residual_blocks=1):
+ super(SimpleAdapter, self).__init__()
+
+ # Pixel Unshuffle: reduce spatial dimensions by a factor of 8
+ self.pixel_unshuffle = nn.PixelUnshuffle(downscale_factor=8)
+
+ # Convolution: reduce spatial dimensions by a factor
+ # of 2 (without overlap)
+ self.conv = nn.Conv2d(in_dim * 64, out_dim, kernel_size=kernel_size, stride=stride, padding=0)
+
+ # Residual blocks for feature extraction
+ self.residual_blocks = nn.Sequential(
+ *[ResidualBlock(out_dim) for _ in range(num_residual_blocks)]
+ )
+
+ def forward(self, x):
+ # Reshape to merge the frame dimension into batch
+ bs, c, f, h, w = x.size()
+ x = x.permute(0, 2, 1, 3, 4).contiguous().view(bs * f, c, h, w)
+
+ # Pixel Unshuffle operation
+ x_unshuffled = self.pixel_unshuffle(x)
+
+ # Convolution operation
+ x_conv = self.conv(x_unshuffled)
+
+ # Feature extraction with residual blocks
+ out = self.residual_blocks(x_conv)
+
+ # Reshape to restore original bf dimension
+ out = out.view(bs, f, out.size(1), out.size(2), out.size(3))
+
+ # Permute dimensions to reorder (if needed), e.g., swap channels and feature frames
+ out = out.permute(0, 2, 1, 3, 4)
+
+ return out
+
+class ResidualBlock(nn.Module):
+ def __init__(self, dim):
+ super(ResidualBlock, self).__init__()
+ self.conv1 = nn.Conv2d(dim, dim, kernel_size=3, padding=1)
+ self.relu = nn.ReLU(inplace=True)
+ self.conv2 = nn.Conv2d(dim, dim, kernel_size=3, padding=1)
+
+ def forward(self, x):
+ residual = x
+ out = self.relu(self.conv1(x))
+ out = self.conv2(out)
+ out += residual
+ return out
+
+# Example usage
+# in_dim = 3
+# out_dim = 64
+# adapter = SimpleAdapterWithReshape(in_dim, out_dim)
+# x = torch.randn(1, in_dim, 4, 64, 64) # e.g., batch size = 1, channels = 3, frames/features = 4
+# output = adapter(x)
+# print(output.shape) # Should reflect transformed dimensions
diff --git a/videox_fun/models/wan_transformer3d.py b/videox_fun/models/wan_transformer3d.py
index a66a405..0f8825b 100755
--- a/videox_fun/models/wan_transformer3d.py
+++ b/videox_fun/models/wan_transformer3d.py
@@ -24,6 +24,7 @@ from ..dist import (get_sequence_parallel_rank,
xFuserLongContextAttention)
from ..dist.wan_xfuser import usp_attn_forward
from .cache_utils import TeaCache
+from .wan_camera_adapter import SimpleAdapter
try:
import flash_attn_interface
@@ -279,6 +280,24 @@ def get_1d_rotary_pos_embed_riflex(
freqs_cis = torch.polar(torch.ones_like(freqs), freqs) # complex64 # [S, D/2]
return freqs_cis
+# Similar to diffusers.pipelines.hunyuandit.pipeline_hunyuandit.get_resize_crop_region_for_grid
+def get_resize_crop_region_for_grid(src, tgt_width, tgt_height):
+ tw = tgt_width
+ th = tgt_height
+ h, w = src
+ r = h / w
+ if r > (th / tw):
+ resize_height = th
+ resize_width = int(round(th / h * w))
+ else:
+ resize_width = tw
+ resize_height = int(round(tw / w * h))
+
+ crop_top = int(round((th - resize_height) / 2.0))
+ crop_left = int(round((tw - resize_width) / 2.0))
+
+ return (crop_top, crop_left), (crop_top + resize_height, crop_left + resize_width)
+
@amp.autocast(enabled=False)
def rope_apply(x, grid_sizes, freqs):
n, c = x.size(2), x.size(3) // 2
@@ -654,6 +673,10 @@ class WanTransformer3DModel(ModelMixin, ConfigMixin, FromOriginalModelMixin):
eps=1e-6,
in_channels=16,
hidden_size=2048,
+ add_control_adapter=False,
+ in_dim_control_adapter=24,
+ add_ref_conv=False,
+ in_dim_ref_conv=16,
):
r"""
Initialize the diffusion model backbone.
@@ -737,6 +760,7 @@ class WanTransformer3DModel(ModelMixin, ConfigMixin, FromOriginalModelMixin):
assert (dim % num_heads) == 0 and (dim // num_heads) % 2 == 0
d = dim // num_heads
self.d = d
+ self.dim = dim
self.freqs = torch.cat(
[
rope_params(1024, d - 4 * (d // 6)),
@@ -748,6 +772,16 @@ class WanTransformer3DModel(ModelMixin, ConfigMixin, FromOriginalModelMixin):
if model_type == 'i2v':
self.img_emb = MLPProj(1280, dim)
+
+ if add_control_adapter:
+ self.control_adapter = SimpleAdapter(in_dim_control_adapter, dim, kernel_size=patch_size[1:], stride=patch_size[1:])
+ else:
+ self.control_adapter = None
+
+ if add_ref_conv:
+ self.ref_conv = nn.Conv2d(in_dim_ref_conv, dim, kernel_size=patch_size[1:], stride=patch_size[1:])
+ else:
+ self.ref_conv = None
self.teacache = None
self.gradient_checkpointing = False
@@ -814,6 +848,8 @@ class WanTransformer3DModel(ModelMixin, ConfigMixin, FromOriginalModelMixin):
seq_len,
clip_fea=None,
y=None,
+ y_camera=None,
+ full_ref=None,
cond_flag=True,
):
r"""
@@ -852,9 +888,21 @@ class WanTransformer3DModel(ModelMixin, ConfigMixin, FromOriginalModelMixin):
# embeddings
x = [self.patch_embedding(u.unsqueeze(0)) for u in x]
+ # add control adapter
+ if self.control_adapter is not None and y_camera is not None:
+ y_camera = self.control_adapter(y_camera)
+ x = [u + v for u, v in zip(x, y_camera)]
+
grid_sizes = torch.stack(
[torch.tensor(u.shape[2:], dtype=torch.long) for u in x])
+
x = [u.flatten(2).transpose(1, 2) for u in x]
+ if self.ref_conv is not None and full_ref is not None:
+ full_ref = self.ref_conv(full_ref).flatten(2).transpose(1, 2)
+ grid_sizes = torch.stack([torch.tensor([u[0] + 1, u[1], u[2]]) for u in grid_sizes]).to(grid_sizes.device)
+ seq_len += full_ref.size(1)
+ x = [torch.concat([_full_ref.unsqueeze(0), u], dim=1) for _full_ref, u in zip(full_ref, x)]
+
seq_lens = torch.tensor([u.size(1) for u in x], dtype=torch.long)
if self.sp_world_size > 1:
seq_len = int(math.ceil(seq_len / self.sp_world_size)) * self.sp_world_size
@@ -997,6 +1045,11 @@ class WanTransformer3DModel(ModelMixin, ConfigMixin, FromOriginalModelMixin):
if self.sp_world_size > 1:
x = get_sp_group().all_gather(x, dim=1)
+ if self.ref_conv is not None and full_ref is not None:
+ full_ref_length = full_ref.size(1)
+ x = x[:, full_ref_length:]
+ grid_sizes = torch.stack([torch.tensor([u[0] - 1, u[1], u[2]]) for u in grid_sizes]).to(grid_sizes.device)
+
# head
x = self.head(x, e)
diff --git a/videox_fun/models/wan_vae.py b/videox_fun/models/wan_vae.py
old mode 100644
new mode 100755
index f25b7ad..08e01d5
--- a/videox_fun/models/wan_vae.py
+++ b/videox_fun/models/wan_vae.py
@@ -14,6 +14,9 @@ from diffusers.models.modeling_utils import ModelMixin
from diffusers.utils.accelerate_utils import apply_forward_hook
from einops import rearrange
+from ..dist import parallel_magvit_vae
+
+
CACHE_T = 2
@@ -546,6 +549,7 @@ class AutoencoderKLWan_(nn.Module):
self.clear_cache()
return x
+ @parallel_magvit_vae(0.2, 8)
def decode(self, z, scale):
self.clear_cache()
# z: [b,c,t,h,w]
diff --git a/videox_fun/pipeline/pipeline_wan_fun.py b/videox_fun/pipeline/pipeline_wan_fun.py
index 62822e3..ea5bcc8 100755
--- a/videox_fun/pipeline/pipeline_wan_fun.py
+++ b/videox_fun/pipeline/pipeline_wan_fun.py
@@ -408,6 +408,7 @@ class WanFunPipeline(DiffusionPipeline):
callback_on_step_end_tensor_inputs: List[str] = ["latents"],
max_sequence_length: int = 512,
comfyui_progressbar: bool = False,
+ cfg_skip_ratio: int = None,
shift: int = 5,
) -> Union[WanPipelineOutput, Tuple]:
"""
@@ -466,7 +467,9 @@ class WanFunPipeline(DiffusionPipeline):
device=device,
)
if do_classifier_free_guidance:
- prompt_embeds = negative_prompt_embeds + prompt_embeds
+ in_prompt_embeds = negative_prompt_embeds + prompt_embeds
+ else:
+ in_prompt_embeds = prompt_embeds
# 4. Prepare timesteps
if isinstance(self.scheduler, FlowMatchEulerDiscreteScheduler):
@@ -512,6 +515,10 @@ class WanFunPipeline(DiffusionPipeline):
num_warmup_steps = max(len(timesteps) - num_inference_steps * self.scheduler.order, 0)
with self.progress_bar(total=num_inference_steps) as progress_bar:
for i, t in enumerate(timesteps):
+ if cfg_skip_ratio is not None and i >= num_inference_steps * (1 - cfg_skip_ratio):
+ do_classifier_free_guidance = False
+ in_prompt_embeds = prompt_embeds
+
if self.interrupt:
continue
@@ -526,7 +533,7 @@ class WanFunPipeline(DiffusionPipeline):
with torch.cuda.amp.autocast(dtype=weight_dtype):
noise_pred = self.transformer(
x=latent_model_input,
- context=prompt_embeds,
+ context=in_prompt_embeds,
t=timestep,
seq_len=seq_len,
)
diff --git a/videox_fun/pipeline/pipeline_wan_fun_control.py b/videox_fun/pipeline/pipeline_wan_fun_control.py
index 2551e91..297b164 100755
--- a/videox_fun/pipeline/pipeline_wan_fun_control.py
+++ b/videox_fun/pipeline/pipeline_wan_fun_control.py
@@ -474,6 +474,8 @@ class WanFunControlPipeline(DiffusionPipeline):
height: int = 480,
width: int = 720,
control_video: Union[torch.FloatTensor] = None,
+ control_camera_video: Union[torch.FloatTensor] = None,
+ start_image: Union[torch.FloatTensor] = None,
ref_image: Union[torch.FloatTensor] = None,
num_frames: int = 49,
num_inference_steps: int = 50,
@@ -495,6 +497,7 @@ class WanFunControlPipeline(DiffusionPipeline):
clip_image: Image = None,
max_sequence_length: int = 512,
comfyui_progressbar: bool = False,
+ cfg_skip_ratio: int = None,
shift: int = 5,
) -> Union[WanPipelineOutput, Tuple]:
"""
@@ -553,7 +556,9 @@ class WanFunControlPipeline(DiffusionPipeline):
device=device,
)
if do_classifier_free_guidance:
- prompt_embeds = negative_prompt_embeds + prompt_embeds
+ in_prompt_embeds = negative_prompt_embeds + prompt_embeds
+ else:
+ in_prompt_embeds = prompt_embeds
# 4. Prepare timesteps
if isinstance(self.scheduler, FlowMatchEulerDiscreteScheduler):
@@ -591,7 +596,22 @@ class WanFunControlPipeline(DiffusionPipeline):
pbar.update(1)
# Prepare mask latent variables
- if control_video is not None:
+ if control_camera_video is not None:
+ control_latents = None
+ # Rearrange dimensions
+ # Concatenate and transpose dimensions
+ control_camera_latents = torch.concat(
+ [
+ torch.repeat_interleave(control_camera_video[:, :, 0:1], repeats=4, dim=2),
+ control_camera_video[:, :, 1:]
+ ], dim=2
+ ).transpose(1, 2)
+
+ # Reshape, transpose, and view into desired shape
+ b, f, c, h, w = control_camera_latents.shape
+ control_camera_latents = control_camera_latents.contiguous().view(b, f // 4, 4, c, h, w).transpose(2, 3)
+ control_camera_latents = control_camera_latents.contiguous().view(b, f // 4, c * 4, h, w).transpose(1, 2)
+ elif control_video is not None:
video_length = control_video.shape[2]
control_video = self.image_processor.preprocess(rearrange(control_video, "b c f h w -> (b f) c h w"), height=height, width=width)
control_video = control_video.to(dtype=torch.float32)
@@ -607,24 +627,20 @@ class WanFunControlPipeline(DiffusionPipeline):
generator,
do_classifier_free_guidance
)[1]
- control_latents = (
- torch.cat([control_video_latents] * 2) if do_classifier_free_guidance else control_video_latents
- ).to(device, weight_dtype)
+ control_camera_latents = None
else:
control_video_latents = torch.zeros_like(latents).to(device, weight_dtype)
- control_latents = (
- torch.cat([control_video_latents] * 2) if do_classifier_free_guidance else control_video_latents
- ).to(device, weight_dtype)
+ control_camera_latents = None
+
+ if start_image is not None:
+ video_length = start_image.shape[2]
+ start_image = self.image_processor.preprocess(rearrange(start_image, "b c f h w -> (b f) c h w"), height=height, width=width)
+ start_image = start_image.to(dtype=torch.float32)
+ start_image = rearrange(start_image, "(b f) c h w -> b c f h w", f=video_length)
- if ref_image is not None:
- video_length = ref_image.shape[2]
- ref_image = self.image_processor.preprocess(rearrange(ref_image, "b c f h w -> (b f) c h w"), height=height, width=width)
- ref_image = ref_image.to(dtype=torch.float32)
- ref_image = rearrange(ref_image, "(b f) c h w -> b c f h w", f=video_length)
-
- ref_image_latentes = self.prepare_control_latents(
+ start_image_latentes = self.prepare_control_latents(
None,
- ref_image,
+ start_image,
batch_size,
height,
width,
@@ -634,35 +650,49 @@ class WanFunControlPipeline(DiffusionPipeline):
do_classifier_free_guidance
)[1]
- ref_image_latentes_conv_in = torch.zeros_like(latents)
+ start_image_latentes_conv_in = torch.zeros_like(latents)
if latents.size()[2] != 1:
- ref_image_latentes_conv_in[:, :, :1] = ref_image_latentes
- ref_image_latentes_conv_in = (
- torch.cat([ref_image_latentes_conv_in] * 2) if do_classifier_free_guidance else ref_image_latentes_conv_in
- ).to(device, weight_dtype)
- control_latents = torch.cat([control_latents, ref_image_latentes_conv_in], dim = 1)
+ start_image_latentes_conv_in[:, :, :1] = start_image_latentes
else:
- ref_image_latentes_conv_in = torch.zeros_like(latents)
- ref_image_latentes_conv_in = (
- torch.cat([ref_image_latentes_conv_in] * 2) if do_classifier_free_guidance else ref_image_latentes_conv_in
- ).to(device, weight_dtype)
- control_latents = torch.cat([control_latents, ref_image_latentes_conv_in], dim = 1)
+ start_image_latentes_conv_in = torch.zeros_like(latents)
# Prepare clip latent variables
if clip_image is not None:
clip_image = TF.to_tensor(clip_image).sub_(0.5).div_(0.5).to(device, weight_dtype)
clip_context = self.clip_image_encoder([clip_image[:, None, :, :]])
- clip_context = (
- torch.cat([clip_context] * 2) if do_classifier_free_guidance else clip_context
- )
else:
clip_image = Image.new("RGB", (512, 512), color=(0, 0, 0))
clip_image = TF.to_tensor(clip_image).sub_(0.5).div_(0.5).to(device, weight_dtype)
clip_context = self.clip_image_encoder([clip_image[:, None, :, :]])
- clip_context = (
- torch.cat([clip_context] * 2) if do_classifier_free_guidance else clip_context
- )
clip_context = torch.zeros_like(clip_context)
+
+ if self.transformer.config.get("add_ref_conv", False):
+ if ref_image is not None:
+ video_length = ref_image.shape[2]
+ ref_image = self.image_processor.preprocess(rearrange(ref_image, "b c f h w -> (b f) c h w"), height=height, width=width)
+ ref_image = ref_image.to(dtype=torch.float32)
+ ref_image = rearrange(ref_image, "(b f) c h w -> b c f h w", f=video_length)
+
+ ref_image_latentes = self.prepare_control_latents(
+ None,
+ ref_image,
+ batch_size,
+ height,
+ width,
+ weight_dtype,
+ device,
+ generator,
+ do_classifier_free_guidance
+ )[1]
+ ref_image_latentes = ref_image_latentes[:, :, 0]
+ else:
+ ref_image_latentes = torch.zeros_like(latents)[:, :, 0]
+ else:
+ if ref_image is not None:
+ raise ValueError("The add_ref_conv is False, but ref_image is not None")
+ else:
+ ref_image_latentes = None
+
if comfyui_progressbar:
pbar.update(1)
@@ -675,6 +705,10 @@ class WanFunControlPipeline(DiffusionPipeline):
num_warmup_steps = max(len(timesteps) - num_inference_steps * self.scheduler.order, 0)
with self.progress_bar(total=num_inference_steps) as progress_bar:
for i, t in enumerate(timesteps):
+ if cfg_skip_ratio is not None and i >= num_inference_steps * (1 - cfg_skip_ratio):
+ do_classifier_free_guidance = False
+ in_prompt_embeds = prompt_embeds
+
if self.interrupt:
continue
@@ -682,6 +716,35 @@ class WanFunControlPipeline(DiffusionPipeline):
if hasattr(self.scheduler, "scale_model_input"):
latent_model_input = self.scheduler.scale_model_input(latent_model_input, t)
+ # Prepare mask latent variables
+ if control_camera_video is not None:
+ control_latents_input = None
+ control_camera_latents_input = (
+ torch.cat([control_camera_latents] * 2) if do_classifier_free_guidance else control_camera_latents
+ ).to(device, weight_dtype)
+ else:
+ control_latents_input = (
+ torch.cat([control_video_latents] * 2) if do_classifier_free_guidance else control_video_latents
+ ).to(device, weight_dtype)
+ control_camera_latents_input = None
+
+ start_image_latentes_conv_in_input = (
+ torch.cat([start_image_latentes_conv_in] * 2) if do_classifier_free_guidance else start_image_latentes_conv_in
+ ).to(device, weight_dtype)
+ control_latents_input = start_image_latentes_conv_in_input if control_latents_input is None else \
+ torch.cat([control_latents_input, start_image_latentes_conv_in_input], dim = 1)
+
+ clip_context_input = (
+ torch.cat([clip_context] * 2) if do_classifier_free_guidance else clip_context
+ )
+
+ if ref_image_latentes is not None:
+ full_ref = (
+ torch.cat([ref_image_latentes] * 2) if do_classifier_free_guidance else ref_image_latentes
+ ).to(device, weight_dtype)
+ else:
+ full_ref = None
+
# broadcast to batch dimension in a way that's compatible with ONNX/Core ML
timestep = t.expand(latent_model_input.shape[0])
@@ -689,11 +752,13 @@ class WanFunControlPipeline(DiffusionPipeline):
with torch.cuda.amp.autocast(dtype=weight_dtype):
noise_pred = self.transformer(
x=latent_model_input,
- context=prompt_embeds,
+ context=in_prompt_embeds,
t=timestep,
seq_len=seq_len,
- y=control_latents,
- clip_fea=clip_context,
+ y=control_latents_input,
+ y_camera=control_camera_latents_input,
+ full_ref=full_ref,
+ clip_fea=clip_context_input,
)
# perform guidance
diff --git a/videox_fun/pipeline/pipeline_wan_fun_inpaint.py b/videox_fun/pipeline/pipeline_wan_fun_inpaint.py
index 0221909..8d63d82 100755
--- a/videox_fun/pipeline/pipeline_wan_fun_inpaint.py
+++ b/videox_fun/pipeline/pipeline_wan_fun_inpaint.py
@@ -496,6 +496,7 @@ class WanFunInpaintPipeline(DiffusionPipeline):
clip_image: Image = None,
max_sequence_length: int = 512,
comfyui_progressbar: bool = False,
+ cfg_skip_ratio: int = None,
shift: int = 5,
) -> Union[WanPipelineOutput, Tuple]:
"""
@@ -554,7 +555,9 @@ class WanFunInpaintPipeline(DiffusionPipeline):
device=device,
)
if do_classifier_free_guidance:
- prompt_embeds = negative_prompt_embeds + prompt_embeds
+ in_prompt_embeds = negative_prompt_embeds + prompt_embeds
+ else:
+ in_prompt_embeds = prompt_embeds
# 4. Prepare timesteps
if isinstance(self.scheduler, FlowMatchEulerDiscreteScheduler):
@@ -606,12 +609,6 @@ class WanFunInpaintPipeline(DiffusionPipeline):
torch.zeros_like(latents)[:, :1].to(device, weight_dtype), [1, 4, 1, 1, 1]
)
masked_video_latents = torch.zeros_like(latents).to(device, weight_dtype)
-
- mask_input = torch.cat([mask_latents] * 2) if do_classifier_free_guidance else mask_latents
- masked_video_latents_input = (
- torch.cat([masked_video_latents] * 2) if do_classifier_free_guidance else masked_video_latents
- )
- y = torch.cat([mask_input, masked_video_latents_input], dim=1).to(device, weight_dtype)
else:
bs, _, video_length, height, width = video.size()
mask_condition = self.mask_processor.preprocess(rearrange(mask_video, "b c f h w -> (b f) c h w"), height=height, width=width)
@@ -642,27 +639,14 @@ class WanFunInpaintPipeline(DiffusionPipeline):
mask_condition = mask_condition.transpose(1, 2)
mask_latents = resize_mask(1 - mask_condition, masked_video_latents, True).to(device, weight_dtype)
- mask_input = torch.cat([mask_latents] * 2) if do_classifier_free_guidance else mask_latents
- masked_video_latents_input = (
- torch.cat([masked_video_latents] * 2) if do_classifier_free_guidance else masked_video_latents
- )
-
- y = torch.cat([mask_input, masked_video_latents_input], dim=1).to(device, weight_dtype)
-
# Prepare clip latent variables
if clip_image is not None:
clip_image = TF.to_tensor(clip_image).sub_(0.5).div_(0.5).to(device, weight_dtype)
clip_context = self.clip_image_encoder([clip_image[:, None, :, :]])
- clip_context = (
- torch.cat([clip_context] * 2) if do_classifier_free_guidance else clip_context
- )
else:
clip_image = Image.new("RGB", (512, 512), color=(0, 0, 0))
clip_image = TF.to_tensor(clip_image).sub_(0.5).div_(0.5).to(device, weight_dtype)
clip_context = self.clip_image_encoder([clip_image[:, None, :, :]])
- clip_context = (
- torch.cat([clip_context] * 2) if do_classifier_free_guidance else clip_context
- )
clip_context = torch.zeros_like(clip_context)
if comfyui_progressbar:
pbar.update(1)
@@ -676,6 +660,10 @@ class WanFunInpaintPipeline(DiffusionPipeline):
num_warmup_steps = max(len(timesteps) - num_inference_steps * self.scheduler.order, 0)
with self.progress_bar(total=num_inference_steps) as progress_bar:
for i, t in enumerate(timesteps):
+ if cfg_skip_ratio is not None and i >= num_inference_steps * (1 - cfg_skip_ratio):
+ do_classifier_free_guidance = False
+ in_prompt_embeds = prompt_embeds
+
if self.interrupt:
continue
@@ -683,6 +671,17 @@ class WanFunInpaintPipeline(DiffusionPipeline):
if hasattr(self.scheduler, "scale_model_input"):
latent_model_input = self.scheduler.scale_model_input(latent_model_input, t)
+ if init_video is not None:
+ mask_input = torch.cat([mask_latents] * 2) if do_classifier_free_guidance else mask_latents
+ masked_video_latents_input = (
+ torch.cat([masked_video_latents] * 2) if do_classifier_free_guidance else masked_video_latents
+ )
+ y = torch.cat([mask_input, masked_video_latents_input], dim=1).to(device, weight_dtype)
+
+ clip_context_input = (
+ torch.cat([clip_context] * 2) if do_classifier_free_guidance else clip_context
+ )
+
# broadcast to batch dimension in a way that's compatible with ONNX/Core ML
timestep = t.expand(latent_model_input.shape[0])
@@ -690,11 +689,11 @@ class WanFunInpaintPipeline(DiffusionPipeline):
with torch.cuda.amp.autocast(dtype=weight_dtype):
noise_pred = self.transformer(
x=latent_model_input,
- context=prompt_embeds,
+ context=in_prompt_embeds,
t=timestep,
seq_len=seq_len,
y=y,
- clip_fea=clip_context,
+ clip_fea=clip_context_input,
)
# perform guidance
diff --git a/videox_fun/ui/wan_fun_ui.py b/videox_fun/ui/wan_fun_ui.py
index bc67205..a775c41 100755
--- a/videox_fun/ui/wan_fun_ui.py
+++ b/videox_fun/ui/wan_fun_ui.py
@@ -188,6 +188,8 @@ class Wan_Fun_Controller(Fun_Controller):
self.pipeline.transformer.enable_teacache(
coefficients, sample_step_slider, self.teacache_threshold, num_skip_start_steps=self.num_skip_start_steps, offload=self.teacache_offload
)
+ else:
+ self.pipeline.transformer.disable_teacache()
if int(seed_textbox) != -1 and seed_textbox != "": torch.manual_seed(int(seed_textbox))
else: seed_textbox = np.random.randint(0, 1e10)
diff --git a/videox_fun/ui/wan_ui.py b/videox_fun/ui/wan_ui.py
index b99b118..c80fdea 100755
--- a/videox_fun/ui/wan_ui.py
+++ b/videox_fun/ui/wan_ui.py
@@ -181,6 +181,8 @@ class Wan_Controller(Fun_Controller):
self.pipeline.transformer.enable_teacache(
coefficients, sample_step_slider, self.teacache_threshold, num_skip_start_steps=self.num_skip_start_steps, offload=self.teacache_offload
)
+ else:
+ self.pipeline.transformer.disable_teacache()
if int(seed_textbox) != -1 and seed_textbox != "": torch.manual_seed(int(seed_textbox))
else: seed_textbox = np.random.randint(0, 1e10)
diff --git a/videox_fun/utils/utils.py b/videox_fun/utils/utils.py
old mode 100644
new mode 100755
index b1a1495..13bf02a
--- a/videox_fun/utils/utils.py
+++ b/videox_fun/utils/utils.py
@@ -233,3 +233,16 @@ def get_video_to_video_latent(input_video_path, video_length, sample_size, fps=N
ref_image = torch.from_numpy(np.array(ref_image))
ref_image = ref_image.unsqueeze(0).permute([3, 0, 1, 2]).unsqueeze(0) / 255
return input_video, input_video_mask, ref_image, clip_image
+
+def get_image_latent(ref_image=None, sample_size=None):
+ if ref_image is not None:
+ if isinstance(ref_image, str):
+ ref_image = Image.open(ref_image).convert("RGB")
+ ref_image = ref_image.resize((sample_size[1], sample_size[0]))
+ ref_image = torch.from_numpy(np.array(ref_image))
+ ref_image = ref_image.unsqueeze(0).permute([3, 0, 1, 2]).unsqueeze(0) / 255
+ else:
+ ref_image = torch.from_numpy(np.array(ref_image))
+ ref_image = ref_image.unsqueeze(0).permute([3, 0, 1, 2]).unsqueeze(0) / 255
+
+ return ref_image
\ No newline at end of file
| | |