diff --git a/.gitignore b/.gitignore
index 82f9275..39cb884 100644
--- a/.gitignore
+++ b/.gitignore
@@ -1,4 +1,11 @@
# Byte-compiled / optimized / DLL files
+models*
+output*
+logs*
+taming*
+samples*
+datasets*
+asset*
__pycache__/
*.py[cod]
*$py.class
@@ -106,10 +113,8 @@ ipython_config.py
#pdm.lock
# pdm stores project-wide configurations in .pdm.toml, but it is recommended to not include it
# in version control.
-# https://pdm.fming.dev/latest/usage/project/#working-with-version-control
+# https://pdm.fming.dev/#use-with-ide
.pdm.toml
-.pdm-python
-.pdm-build/
# PEP 582; used by e.g. github.com/David-OConnor/pyflow and github.com/pdm-project/pdm
__pypackages__/
diff --git a/README.md b/README.md
index bf406ff..1b8c489 100644
--- a/README.md
+++ b/README.md
@@ -1,2 +1,219 @@
# CogVideoX-Fun
-📹 A more flexible CogVideoX that can generate videos of any resolution and image-to-video content.
+
+😊 Welcome!
+
+English | [简体中文](./README_zh-CN.md)
+
+# Table of Contents
+- [Table of Contents](#table-of-contents)
+- [Introduction](#introduction)
+- [Quick Start](#quick-start)
+- [How to use](#how-to-use)
+- [Model zoo](#model-zoo)
+- [TODO List](#todo-list)
+- [Reference](#reference)
+- [License](#license)
+
+# Introduction
+CogVideoX-Fun is a modified pipeline based on the CogVideoX structure, designed to provide more flexibility in generation. It can be used to create AI images and videos, as well as to train baseline models and Lora models for Diffusion Transformer. We support predictions directly from the already trained CogVideoX-Fun model, allowing the generation of videos at different resolutions, approximately 6 seconds long with 8 fps (1 to 49 frames). Users can also train their own baseline models and Lora models to achieve certain style transformations.
+
+We will support quick pull-ups from different platforms, refer to [Quick Start](#quick-start).
+
+What's New:
+- Create code! Now supporting Windows and Linux. Supports video generation at any resolution from 256x256x49 to 1024x1024x49. [ 2024.09.09 ]
+
+Function:
+- [Data Preprocessing](#data-preprocess)
+- [Train DiT](#dit-train)
+- [Video Generation](#video-gen)
+
+These are our generated results [GALLERY](scripts/Result_Gallery.md) (Click the image below to see the video):
+
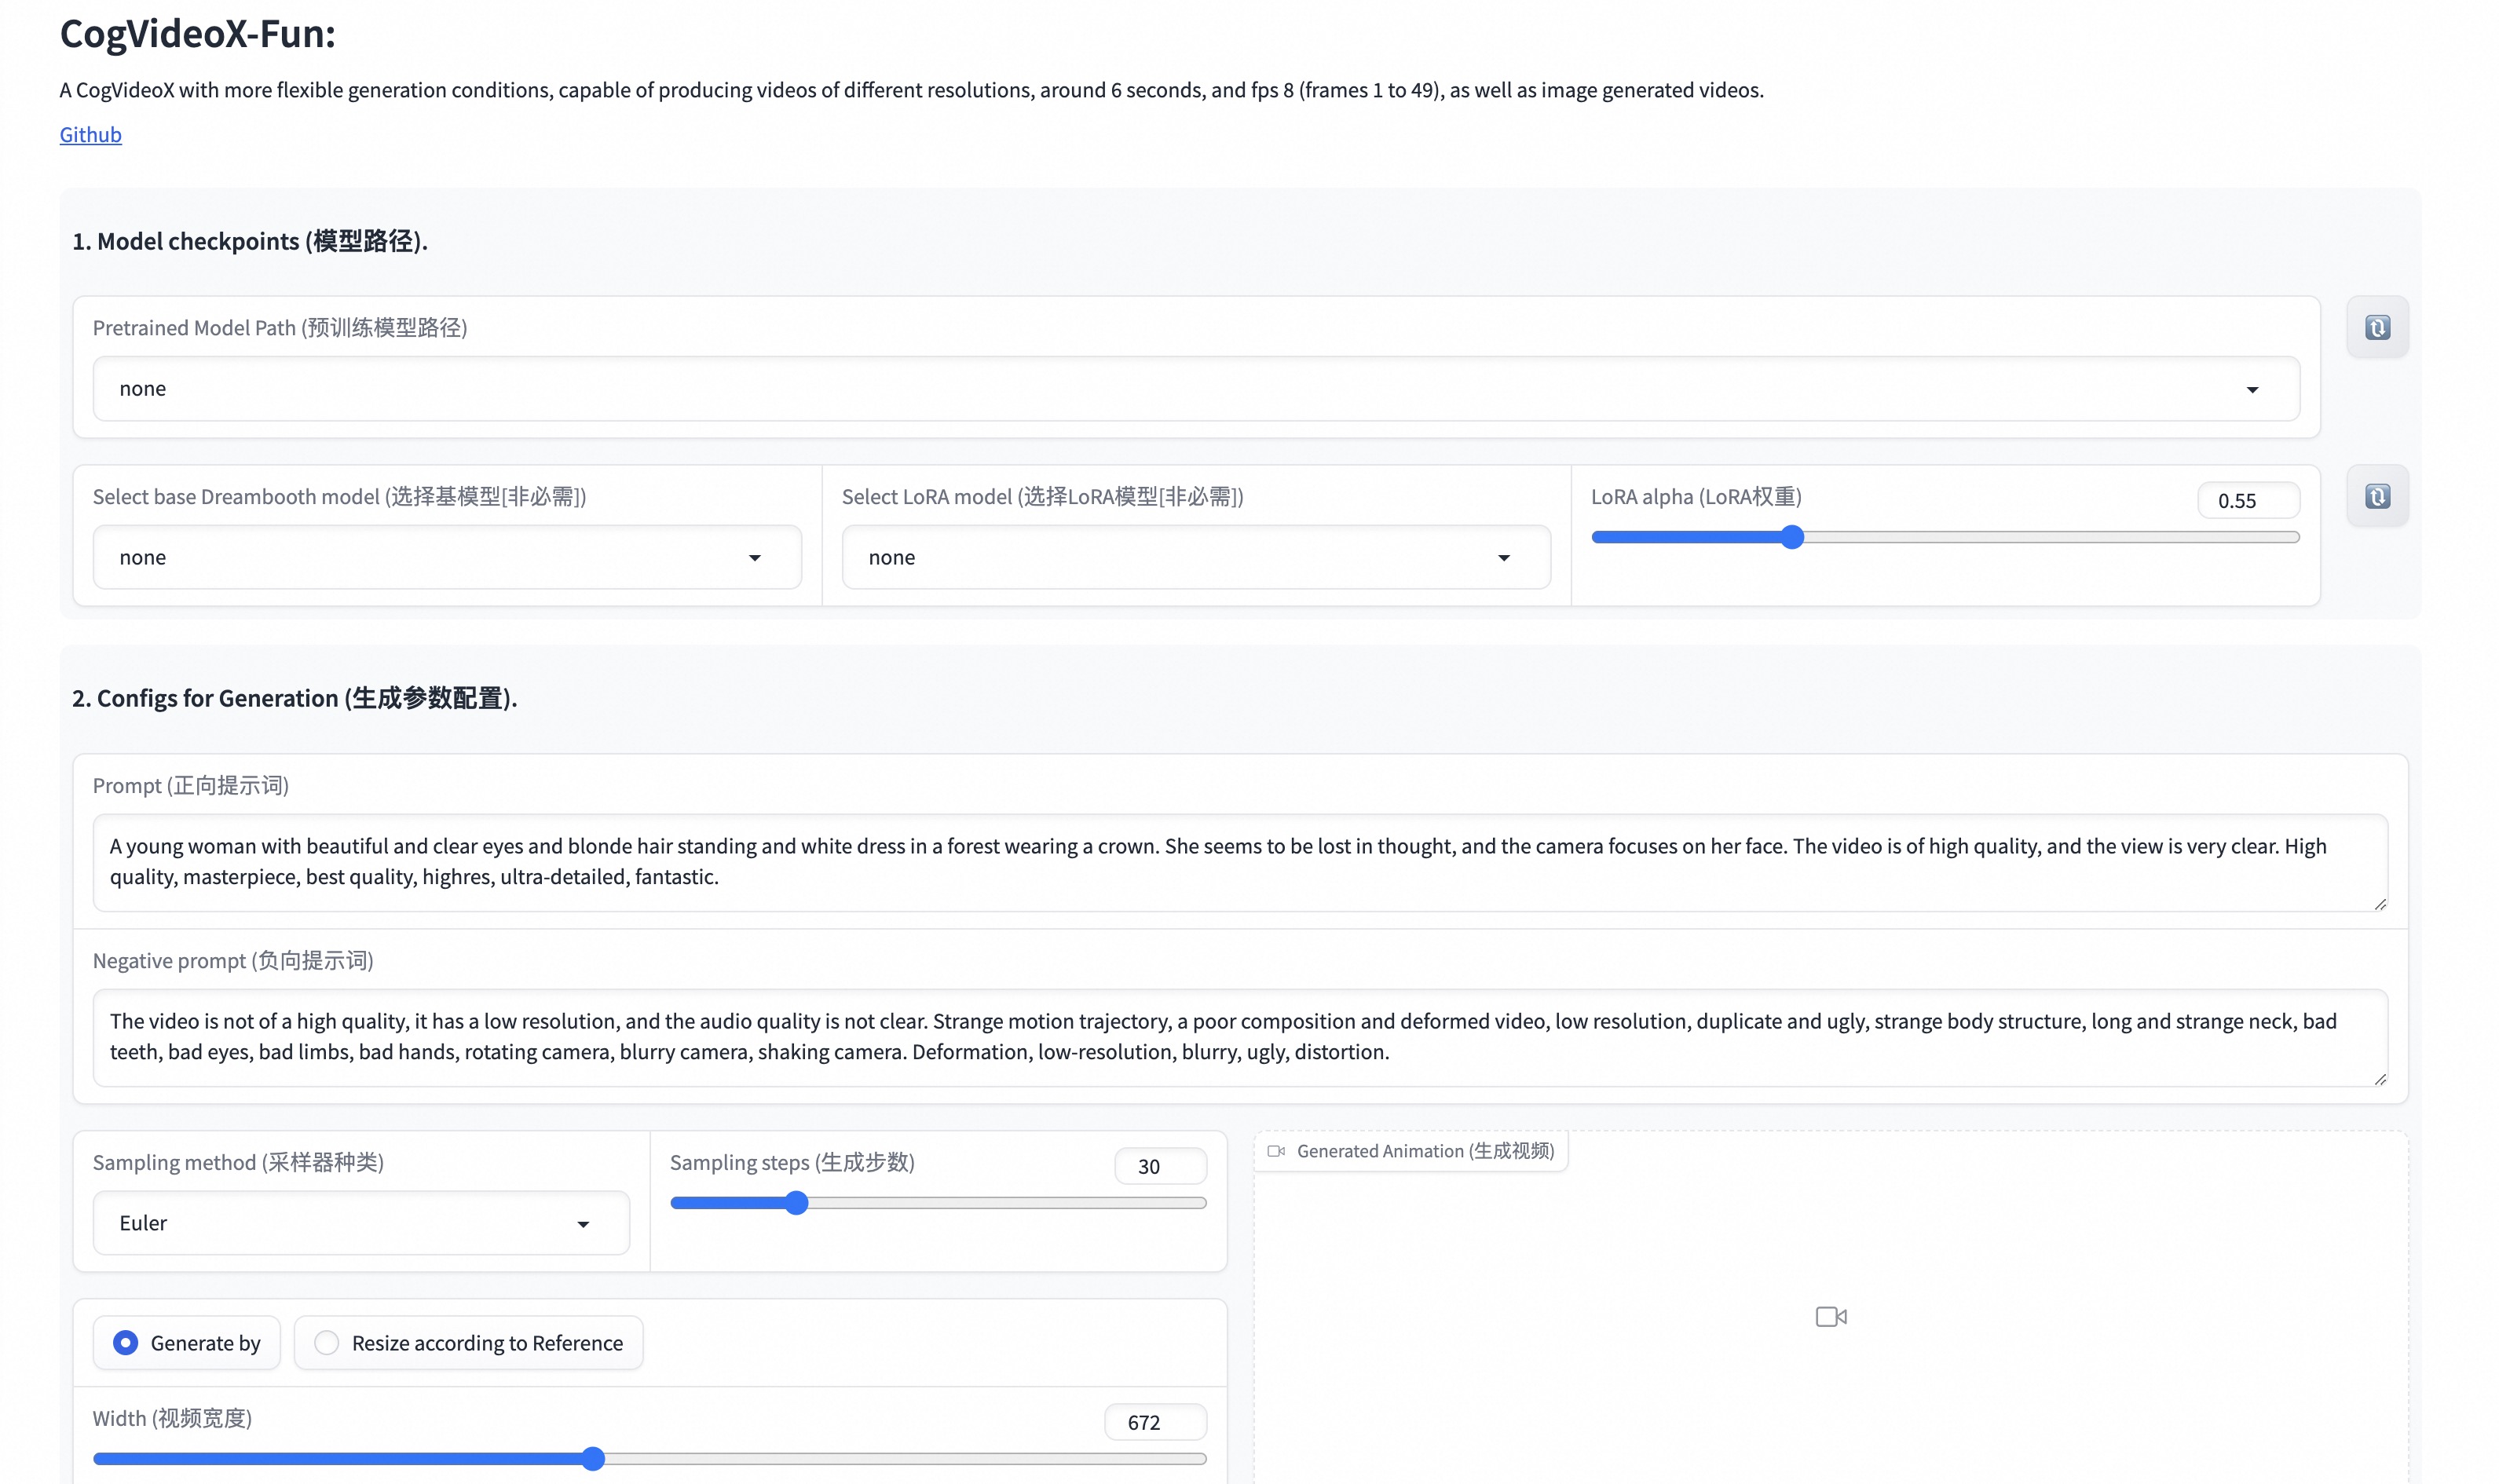
+Our UI interface is as follows:
+
+
+# Quick Start
+### 1. Cloud usage: AliyunDSW/Docker
+#### a. From AliyunDSW
+On the way.
+
+#### b. From ComfyUI
+Our ComfyUI is as follows, please refer to [ComfyUI README](comfyui/README.md) for details.
+
+
+#### c. From docker
+If you are using docker, please make sure that the graphics card driver and CUDA environment have been installed correctly in your machine.
+
+Then execute the following commands in this way:
+
+```
+# pull image
+docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
+
+# enter image
+docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
+
+# clone code
+git clone https://github.com/aigc-apps/CogVideoX-Fun.git
+
+# enter CogVideoX-Fun's dir
+cd CogVideoX-Fun
+
+# download weights
+mkdir models/Diffusion_Transformer
+mkdir models/Personalized_Model
+
+wget https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz -O models/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz
+
+cd models/Diffusion_Transformer/
+tar -xvf CogVideoX-Fun-2b-InP.tar.gz
+cd ../../
+```
+
+### 2. Local install: Environment Check/Downloading/Installation
+#### a. Environment Check
+We have verified CogVideoX-Fun execution on the following environment:
+
+The detailed of Windows:
+- OS: Windows 10
+- python: python3.10 & python3.11
+- pytorch: torch2.2.0
+- CUDA: 11.8 & 12.1
+- CUDNN: 8+
+- GPU: Nvidia-3060 12G & Nvidia-3090 24G
+
+The detailed of Linux:
+- OS: Ubuntu 20.04, CentOS
+- python: python3.10 & python3.11
+- pytorch: torch2.2.0
+- CUDA: 11.8 & 12.1
+- CUDNN: 8+
+- GPU:Nvidia-V100 16G & Nvidia-A10 24G & Nvidia-A100 40G & Nvidia-A100 80G
+
+We need about 60GB available on disk (for saving weights), please check!
+
+#### b. Weights
+We'd better place the [weights](#model-zoo) along the specified path:
+
+EasyAnimateV4:
+```
+📦 models/
+├── 📂 Diffusion_Transformer/
+│ └── 📂 CogVideoX-Fun-2b-InP/
+├── 📂 Personalized_Model/
+│ └── your trained trainformer model / your trained lora model (for UI load)
+```
+
+# How to use
+
+1. Inference
+
+#### a. Using Python Code
+- Step 1: Download the corresponding [weights](#model-zoo) and place them in the models folder.
+- Step 2: Modify prompt, neg_prompt, guidance_scale, and seed in the predict_t2v.py file.
+- Step 3: Run the predict_t2v.py file, wait for the generated results, and save the results in the samples/easyanimate-videos-t2v folder.
+- Step 4: If you want to combine other backbones you have trained with Lora, modify the predict_t2v.py and Lora_path in predict_t2v.py depending on the situation.
+
+#### b. Using webui
+- Step 1: Download the corresponding [weights](#model-zoo) and place them in the models folder.
+- Step 2: Run the app.py file to enter the graph page.
+- Step 3: Select the generated model based on the page, fill in prompt, neg_prompt, guidance_scale, and seed, click on generate, wait for the generated result, and save the result in the samples folder.
+
+#### c. From ComfyUI
+Please refer to [ComfyUI README](comfyui/README.md) for details.
+
+### 2. Model Training
+A complete CogVideoX-Fun training pipeline should include data preprocessing, and Video DiT training.
+
+a. data preprocessing
+
+We have provided a simple demo of training the Lora model through image data, which can be found in the [wiki](https://github.com/aigc-apps/CogVideoX-Fun/wiki/Training-Lora) for details.
+
+A complete data preprocessing link for long video segmentation, cleaning, and description can refer to [README](cogvideox/video_caption/README.md) in the video captions section.
+
+If you want to train a text to image and video generation model. You need to arrange the dataset in this format.
+
+```
+📦 project/
+├── 📂 datasets/
+│ ├── 📂 internal_datasets/
+│ ├── 📂 train/
+│ │ ├── 📄 00000001.mp4
+│ │ ├── 📄 00000002.jpg
+│ │ └── 📄 .....
+│ └── 📄 json_of_internal_datasets.json
+```
+
+The json_of_internal_datasets.json is a standard JSON file. The file_path in the json can to be set as relative path, as shown in below:
+```json
+[
+ {
+ "file_path": "train/00000001.mp4",
+ "text": "A group of young men in suits and sunglasses are walking down a city street.",
+ "type": "video"
+ },
+ {
+ "file_path": "train/00000002.jpg",
+ "text": "A group of young men in suits and sunglasses are walking down a city street.",
+ "type": "image"
+ },
+ .....
+]
+```
+
+You can also set the path as absolute path as follow:
+```json
+[
+ {
+ "file_path": "/mnt/data/videos/00000001.mp4",
+ "text": "A group of young men in suits and sunglasses are walking down a city street.",
+ "type": "video"
+ },
+ {
+ "file_path": "/mnt/data/train/00000001.jpg",
+ "text": "A group of young men in suits and sunglasses are walking down a city street.",
+ "type": "image"
+ },
+ .....
+]
+```
+
+b. Video DiT training
+
+If the data format is relative path during data preprocessing, please set ```scripts/train.sh``` as follow.
+```
+export DATASET_NAME="datasets/internal_datasets/"
+export DATASET_META_NAME="datasets/internal_datasets/json_of_internal_datasets.json"
+```
+
+If the data format is absolute path during data preprocessing, please set ```scripts/train.sh``` as follow.
+```
+export DATASET_NAME=""
+export DATASET_META_NAME="/mnt/data/json_of_internal_datasets.json"
+```
+
+Then, we run scripts/train.sh.
+```sh
+sh scripts/train.sh
+```
+
+For details on setting some parameters, please refer to [Readme Train](scripts/README_TRAIN.md) and [Readme Lora](scripts/README_TRAIN_LORA.md).
+
+
+# Model zoo
+
+| Name | Storage Space | Url | Hugging Face | Description |
+|--|--|--|--|--|
+| CogVideoX-Fun-2b-InP.tar.gz | Before extraction:9.69 GB \/ After extraction: 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 144 frames at a rate of 24 frames per second. |
+
+# TODO List
+- Support CogVideoX-5b.
+
+# Reference
+- CogVideo: https://github.com/THUDM/CogVideo/
+- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
+
+# License
+This project is licensed under the [Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE).
+
+The CogVideoX-2B model (including its corresponding Transformers module and VAE module) is released under the [Apache 2.0 License](LICENSE).
\ No newline at end of file
diff --git a/README_zh-CN.md b/README_zh-CN.md
new file mode 100644
index 0000000..deefe42
--- /dev/null
+++ b/README_zh-CN.md
@@ -0,0 +1,216 @@
+# CogVideoX-Fun
+
+😊 Welcome!
+
+[English](./README.md) | 简体中文
+
+# 目录
+- [目录](#目录)
+- [简介](#简介)
+- [快速启动](#快速启动)
+- [如何使用](#如何使用)
+- [模型地址](#模型地址)
+- [未来计划](#未来计划)
+- [参考文献](#参考文献)
+- [许可证](#许可证)
+
+# 简介
+CogVideoX-Fun是一个基于CogVideoX结构修改后的的pipeline,是一个生成条件更自由的CogVideoX,可用于生成AI图片与视频、训练Diffusion Transformer的基线模型与Lora模型,我们支持从已经训练好的CogVideoX-Fun模型直接进行预测,生成不同分辨率,6秒左右、fps8的视频(1 ~ 49帧),也支持用户训练自己的基线模型与Lora模型,进行一定的风格变换。
+
+我们会逐渐支持从不同平台快速启动,请参阅 [快速启动](#快速启动)。
+
+新特性:
+- 创建代码!现在支持 Windows 和 Linux。支持最大256x256x49到1024x1024x49的任意分辨率的视频生成。[ 2024.09.09 ]
+
+功能概览:
+- [数据预处理](#data-preprocess)
+- [训练DiT](#dit-train)
+- [模型生成](#video-gen)
+
+这些是我们的生成结果 [GALLERY](scripts/Result_Gallery.md) (点击下方的图片可查看视频):
+
+我们的ui界面如下:
+
+
+# 快速启动
+### 1. 云使用: AliyunDSW/Docker
+#### a. 通过阿里云 DSW
+正在路上
+
+#### b. 通过ComfyUI
+我们的ComfyUI界面如下,具体查看[ComfyUI README](comfyui/README.md)。
+
+
+#### c. 通过docker
+使用docker的情况下,请保证机器中已经正确安装显卡驱动与CUDA环境,然后以此执行以下命令:
+
+```
+# pull image
+docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
+
+# enter image
+docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
+
+# clone code
+git clone https://github.com/aigc-apps/CogVideoX-Fun.git
+
+# enter CogVideoX-Fun's dir
+cd CogVideoX-Fun
+
+# download weights
+mkdir models/Diffusion_Transformer
+mkdir models/Personalized_Model
+
+wget https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz -O models/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz
+
+cd models/Diffusion_Transformer/
+tar -xvf CogVideoX-Fun-2b-InP.tar.gz
+cd ../../
+```
+
+### 2. 本地安装: 环境检查/下载/安装
+#### a. 环境检查
+我们已验证CogVideoX-Fun可在以下环境中执行:
+
+Windows 的详细信息:
+- 操作系统 Windows 10
+- python: python3.10 & python3.11
+- pytorch: torch2.2.0
+- CUDA: 11.8 & 12.1
+- CUDNN: 8+
+- GPU: Nvidia-3060 12G & Nvidia-3090 24G
+
+Linux 的详细信息:
+- 操作系统 Ubuntu 20.04, CentOS
+- python: python3.10 & python3.11
+- pytorch: torch2.2.0
+- CUDA: 11.8 & 12.1
+- CUDNN: 8+
+- GPU:Nvidia-V100 16G & Nvidia-A10 24G & Nvidia-A100 40G & Nvidia-A100 80G
+
+我们需要大约 60GB 的可用磁盘空间,请检查!
+
+#### b. 权重放置
+我们最好将[权重](#model-zoo)按照指定路径进行放置:
+
+```
+📦 models/
+├── 📂 Diffusion_Transformer/
+│ └── 📂 CogVideoX-Fun-2b-InP/
+├── 📂 Personalized_Model/
+│ └── your trained trainformer model / your trained lora model (for UI load)
+```
+
+# 如何使用
+
+1. 生成
+
+#### a. 视频生成
+##### i、运行python文件
+- 步骤1:下载对应[权重](#model-zoo)放入models文件夹。
+- 步骤2:在predict_t2v.py文件中修改prompt、neg_prompt、guidance_scale和seed。
+- 步骤3:运行predict_t2v.py文件,等待生成结果,结果保存在samples/cogvideox-videos-t2v文件夹中。
+- 步骤4:如果想结合自己训练的其他backbone与Lora,则看情况修改predict_t2v.py中的predict_t2v.py和lora_path。
+
+##### ii、通过ui界面
+- 步骤1:下载对应[权重](#model-zoo)放入models文件夹。
+- 步骤2:运行app.py文件,进入gradio页面。
+- 步骤3:根据页面选择生成模型,填入prompt、neg_prompt、guidance_scale和seed等,点击生成,等待生成结果,结果保存在sample文件夹中。
+
+##### iii、通过comfyui
+具体查看[ComfyUI README](comfyui/README.md)。
+
+### 2. 模型训练
+一个完整的CogVideoX-Fun训练链路应该包括数据预处理和Video DiT训练。
+
+a.数据预处理
+我们给出了一个简单的demo通过图片数据训练lora模型,详情可以查看[wiki](https://github.com/aigc-apps/CogVideoX-Fun/wiki/Training-Lora)。
+
+一个完整的长视频切分、清洗、描述的数据预处理链路可以参考video caption部分的[README](cogvideox/video_caption/README.md)进行。
+
+如果期望训练一个文生图视频的生成模型,您需要以这种格式排列数据集。
+```
+📦 project/
+├── 📂 datasets/
+│ ├── 📂 internal_datasets/
+│ ├── 📂 train/
+│ │ ├── 📄 00000001.mp4
+│ │ ├── 📄 00000002.jpg
+│ │ └── 📄 .....
+│ └── 📄 json_of_internal_datasets.json
+```
+
+json_of_internal_datasets.json是一个标准的json文件。json中的file_path可以被设置为相对路径,如下所示:
+```json
+[
+ {
+ "file_path": "train/00000001.mp4",
+ "text": "A group of young men in suits and sunglasses are walking down a city street.",
+ "type": "video"
+ },
+ {
+ "file_path": "train/00000002.jpg",
+ "text": "A group of young men in suits and sunglasses are walking down a city street.",
+ "type": "image"
+ },
+ .....
+]
+```
+
+你也可以将路径设置为绝对路径:
+```json
+[
+ {
+ "file_path": "/mnt/data/videos/00000001.mp4",
+ "text": "A group of young men in suits and sunglasses are walking down a city street.",
+ "type": "video"
+ },
+ {
+ "file_path": "/mnt/data/train/00000001.jpg",
+ "text": "A group of young men in suits and sunglasses are walking down a city street.",
+ "type": "image"
+ },
+ .....
+]
+```
+b. Video DiT训练
+
+如果数据预处理时,数据的格式为相对路径,则进入scripts/train.sh进行如下设置。
+```
+export DATASET_NAME="datasets/internal_datasets/"
+export DATASET_META_NAME="datasets/internal_datasets/json_of_internal_datasets.json"
+
+...
+
+train_data_format="normal"
+```
+
+如果数据的格式为绝对路径,则进入scripts/train.sh进行如下设置。
+```
+export DATASET_NAME=""
+export DATASET_META_NAME="/mnt/data/json_of_internal_datasets.json"
+```
+
+最后运行scripts/train.sh。
+```sh
+sh scripts/train.sh
+```
+
+关于一些参数的设置细节,可以查看[Readme Train](scripts/README_TRAIN.md)与[Readme Lora](scripts/README_TRAIN_LORA.md)
+
+# 模型地址
+| 名称 | 存储空间 | 下载地址 | Hugging Face | 描述 |
+|--|--|--|--|--|
+| CogVideoX-Fun-2b-InP.tar.gz | 解压前 9.69 GB / 解压后 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP)| 官方的图生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以144帧、每秒24帧进行训练 |
+
+# 未来计划
+- 支持CogVideoX-5b。
+
+# 参考文献
+- CogVideo: https://github.com/THUDM/CogVideo/
+- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
+
+# 许可证
+本项目采用 [Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE).
+
+CogVideoX-2B 模型 (包括其对应的Transformers模块,VAE模块) 根据 [Apache 2.0 协议](LICENSE) 许可证发布。
\ No newline at end of file
diff --git a/__init__.py b/__init__.py
new file mode 100644
index 0000000..273bba3
--- /dev/null
+++ b/__init__.py
@@ -0,0 +1,3 @@
+from .comfyui.comfyui_nodes import NODE_CLASS_MAPPINGS, NODE_DISPLAY_NAME_MAPPINGS
+
+__all__ = ["NODE_CLASS_MAPPINGS", "NODE_DISPLAY_NAME_MAPPINGS"]
diff --git a/app.py b/app.py
new file mode 100644
index 0000000..a453e7d
--- /dev/null
+++ b/app.py
@@ -0,0 +1,46 @@
+import time
+import torch
+
+from cogvideox.api.api import infer_forward_api, update_diffusion_transformer_api, update_edition_api
+from cogvideox.ui.ui import ui_modelscope, ui_eas, ui
+
+if __name__ == "__main__":
+ # Choose the ui mode
+ ui_mode = "normal"
+
+ # Low gpu memory mode, this is used when the GPU memory is under 16GB
+ low_gpu_memory_mode = False
+ # Use torch.float16 if GPU does not support torch.bfloat16
+ # ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
+ weight_dtype = torch.bfloat16
+
+ # Server ip
+ server_name = "0.0.0.0"
+ server_port = 7860
+
+ # Params below is used when ui_mode = "modelscope"
+ model_name = "models/Diffusion_Transformer/CogVideoX-Fun-2b-InP"
+ savedir_sample = "samples"
+
+ if ui_mode == "modelscope":
+ demo, controller = ui_modelscope(model_name, savedir_sample, low_gpu_memory_mode, weight_dtype)
+ elif ui_mode == "eas":
+ demo, controller = ui_eas(model_name, savedir_sample)
+ else:
+ demo, controller = ui(low_gpu_memory_mode, weight_dtype)
+
+ # launch gradio
+ app, _, _ = demo.queue(status_update_rate=1).launch(
+ server_name=server_name,
+ server_port=server_port,
+ prevent_thread_lock=True
+ )
+
+ # launch api
+ infer_forward_api(None, app, controller)
+ update_diffusion_transformer_api(None, app, controller)
+ update_edition_api(None, app, controller)
+
+ # not close the python
+ while True:
+ time.sleep(5)
\ No newline at end of file
diff --git a/cogvideox/__init__.py b/cogvideox/__init__.py
new file mode 100644
index 0000000..e69de29
diff --git a/cogvideox/api/api.py b/cogvideox/api/api.py
new file mode 100644
index 0000000..24d24fd
--- /dev/null
+++ b/cogvideox/api/api.py
@@ -0,0 +1,149 @@
+import io
+import gc
+import base64
+import torch
+import gradio as gr
+import tempfile
+import hashlib
+import os
+
+from fastapi import FastAPI
+from io import BytesIO
+from PIL import Image
+
+# Function to encode a file to Base64
+def encode_file_to_base64(file_path):
+ with open(file_path, "rb") as file:
+ # Encode the data to Base64
+ file_base64 = base64.b64encode(file.read())
+ return file_base64
+
+def update_edition_api(_: gr.Blocks, app: FastAPI, controller):
+ @app.post("/cogvideox_fun/update_edition")
+ def _update_edition_api(
+ datas: dict,
+ ):
+ edition = datas.get('edition', 'v2')
+
+ try:
+ controller.update_edition(
+ edition
+ )
+ comment = "Success"
+ except Exception as e:
+ torch.cuda.empty_cache()
+ comment = f"Error. error information is {str(e)}"
+
+ return {"message": comment}
+
+def update_diffusion_transformer_api(_: gr.Blocks, app: FastAPI, controller):
+ @app.post("/cogvideox_fun/update_diffusion_transformer")
+ def _update_diffusion_transformer_api(
+ datas: dict,
+ ):
+ diffusion_transformer_path = datas.get('diffusion_transformer_path', 'none')
+
+ try:
+ controller.update_diffusion_transformer(
+ diffusion_transformer_path
+ )
+ comment = "Success"
+ except Exception as e:
+ torch.cuda.empty_cache()
+ comment = f"Error. error information is {str(e)}"
+
+ return {"message": comment}
+
+def save_base64_video(base64_string):
+ video_data = base64.b64decode(base64_string)
+
+ md5_hash = hashlib.md5(video_data).hexdigest()
+ filename = f"{md5_hash}.mp4"
+
+ temp_dir = tempfile.gettempdir()
+ file_path = os.path.join(temp_dir, filename)
+
+ with open(file_path, 'wb') as video_file:
+ video_file.write(video_data)
+
+ return file_path
+
+def infer_forward_api(_: gr.Blocks, app: FastAPI, controller):
+ @app.post("/cogvideox_fun/infer_forward")
+ def _infer_forward_api(
+ datas: dict,
+ ):
+ base_model_path = datas.get('base_model_path', 'none')
+ lora_model_path = datas.get('lora_model_path', 'none')
+ lora_alpha_slider = datas.get('lora_alpha_slider', 0.55)
+ prompt_textbox = datas.get('prompt_textbox', None)
+ negative_prompt_textbox = datas.get('negative_prompt_textbox', 'The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion.')
+ sampler_dropdown = datas.get('sampler_dropdown', 'Euler')
+ sample_step_slider = datas.get('sample_step_slider', 30)
+ resize_method = datas.get('resize_method', "Generate by")
+ width_slider = datas.get('width_slider', 672)
+ height_slider = datas.get('height_slider', 384)
+ base_resolution = datas.get('base_resolution', 512)
+ is_image = datas.get('is_image', False)
+ generation_method = datas.get('generation_method', False)
+ length_slider = datas.get('length_slider', 144)
+ overlap_video_length = datas.get('overlap_video_length', 4)
+ partial_video_length = datas.get('partial_video_length', 72)
+ cfg_scale_slider = datas.get('cfg_scale_slider', 6)
+ start_image = datas.get('start_image', None)
+ end_image = datas.get('end_image', None)
+ validation_video = datas.get('validation_video', None)
+ denoise_strength = datas.get('denoise_strength', 0.70)
+ seed_textbox = datas.get("seed_textbox", 43)
+
+ generation_method = "Image Generation" if is_image else generation_method
+
+ if start_image is not None:
+ start_image = base64.b64decode(start_image)
+ start_image = [Image.open(BytesIO(start_image))]
+
+ if end_image is not None:
+ end_image = base64.b64decode(end_image)
+ end_image = [Image.open(BytesIO(end_image))]
+
+ if validation_video is not None:
+ validation_video = save_base64_video(validation_video)
+
+ try:
+ save_sample_path, comment = controller.generate(
+ "",
+ base_model_path,
+ lora_model_path,
+ lora_alpha_slider,
+ prompt_textbox,
+ negative_prompt_textbox,
+ sampler_dropdown,
+ sample_step_slider,
+ resize_method,
+ width_slider,
+ height_slider,
+ base_resolution,
+ generation_method,
+ length_slider,
+ overlap_video_length,
+ partial_video_length,
+ cfg_scale_slider,
+ start_image,
+ end_image,
+ validation_video,
+ denoise_strength,
+ seed_textbox,
+ is_api = True,
+ )
+ except Exception as e:
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.ipc_collect()
+ save_sample_path = ""
+ comment = f"Error. error information is {str(e)}"
+ return {"message": comment}
+
+ if save_sample_path != "":
+ return {"message": comment, "save_sample_path": save_sample_path, "base64_encoding": encode_file_to_base64(save_sample_path)}
+ else:
+ return {"message": comment, "save_sample_path": save_sample_path}
\ No newline at end of file
diff --git a/cogvideox/api/post_infer.py b/cogvideox/api/post_infer.py
new file mode 100644
index 0000000..41287f5
--- /dev/null
+++ b/cogvideox/api/post_infer.py
@@ -0,0 +1,96 @@
+import base64
+import json
+import sys
+import time
+from datetime import datetime
+from io import BytesIO
+
+import cv2
+import requests
+import base64
+
+
+def post_diffusion_transformer(diffusion_transformer_path, url='http://127.0.0.1:7860'):
+ datas = json.dumps({
+ "diffusion_transformer_path": diffusion_transformer_path
+ })
+ r = requests.post(f'{url}/cogvideox_fun/update_diffusion_transformer', data=datas, timeout=1500)
+ data = r.content.decode('utf-8')
+ return data
+
+def post_update_edition(edition, url='http://0.0.0.0:7860'):
+ datas = json.dumps({
+ "edition": edition
+ })
+ r = requests.post(f'{url}/cogvideox_fun/update_edition', data=datas, timeout=1500)
+ data = r.content.decode('utf-8')
+ return data
+
+def post_infer(generation_method, length_slider, url='http://127.0.0.1:7860'):
+ datas = json.dumps({
+ "base_model_path": "none",
+ "motion_module_path": "none",
+ "lora_model_path": "none",
+ "lora_alpha_slider": 0.55,
+ "prompt_textbox": "This video shows Mount saint helens, washington - the stunning scenery of a rocky mountains during golden hours - wide shot. A soaring drone footage captures the majestic beauty of a coastal cliff, its red and yellow stratified rock faces rich in color and against the vibrant turquoise of the sea.",
+ "negative_prompt_textbox": "Strange motion trajectory, a poor composition and deformed video, worst quality, normal quality, low quality, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera",
+ "sampler_dropdown": "Euler",
+ "sample_step_slider": 30,
+ "width_slider": 672,
+ "height_slider": 384,
+ "generation_method": "Video Generation",
+ "length_slider": length_slider,
+ "cfg_scale_slider": 6,
+ "seed_textbox": 43,
+ })
+ r = requests.post(f'{url}/cogvideox_fun/infer_forward', data=datas, timeout=1500)
+ data = r.content.decode('utf-8')
+ return data
+
+if __name__ == '__main__':
+ # initiate time
+ now_date = datetime.now()
+ time_start = time.time()
+
+ # -------------------------- #
+ # Step 1: update edition
+ # -------------------------- #
+ edition = "v3"
+ outputs = post_update_edition(edition)
+ print('Output update edition: ', outputs)
+
+ # -------------------------- #
+ # Step 2: update edition
+ # -------------------------- #
+ diffusion_transformer_path = "models/Diffusion_Transformer/cogvideox_funV3-XL-2-512x512"
+ outputs = post_diffusion_transformer(diffusion_transformer_path)
+ print('Output update edition: ', outputs)
+
+ # -------------------------- #
+ # Step 3: infer
+ # -------------------------- #
+ # "Video Generation" and "Image Generation"
+ generation_method = "Video Generation"
+ length_slider = 72
+ outputs = post_infer(generation_method, length_slider)
+
+ # Get decoded data
+ outputs = json.loads(outputs)
+ base64_encoding = outputs["base64_encoding"]
+ decoded_data = base64.b64decode(base64_encoding)
+
+ is_image = True if generation_method == "Image Generation" else False
+ if is_image or length_slider == 1:
+ file_path = "1.png"
+ else:
+ file_path = "1.mp4"
+ with open(file_path, "wb") as file:
+ file.write(decoded_data)
+
+ # End of record time
+ # The calculated time difference is the execution time of the program, expressed in seconds / s
+ time_end = time.time()
+ time_sum = (time_end - time_start) % 60
+ print('# --------------------------------------------------------- #')
+ print(f'# Total expenditure: {time_sum}s')
+ print('# --------------------------------------------------------- #')
\ No newline at end of file
diff --git a/cogvideox/data/bucket_sampler.py b/cogvideox/data/bucket_sampler.py
new file mode 100644
index 0000000..2c5fded
--- /dev/null
+++ b/cogvideox/data/bucket_sampler.py
@@ -0,0 +1,379 @@
+# Copyright (c) OpenMMLab. All rights reserved.
+import os
+from typing import (Generic, Iterable, Iterator, List, Optional, Sequence,
+ Sized, TypeVar, Union)
+
+import cv2
+import numpy as np
+import torch
+from PIL import Image
+from torch.utils.data import BatchSampler, Dataset, Sampler
+
+ASPECT_RATIO_512 = {
+ '0.25': [256.0, 1024.0], '0.26': [256.0, 992.0], '0.27': [256.0, 960.0], '0.28': [256.0, 928.0],
+ '0.32': [288.0, 896.0], '0.33': [288.0, 864.0], '0.35': [288.0, 832.0], '0.4': [320.0, 800.0],
+ '0.42': [320.0, 768.0], '0.48': [352.0, 736.0], '0.5': [352.0, 704.0], '0.52': [352.0, 672.0],
+ '0.57': [384.0, 672.0], '0.6': [384.0, 640.0], '0.68': [416.0, 608.0], '0.72': [416.0, 576.0],
+ '0.78': [448.0, 576.0], '0.82': [448.0, 544.0], '0.88': [480.0, 544.0], '0.94': [480.0, 512.0],
+ '1.0': [512.0, 512.0], '1.07': [512.0, 480.0], '1.13': [544.0, 480.0], '1.21': [544.0, 448.0],
+ '1.29': [576.0, 448.0], '1.38': [576.0, 416.0], '1.46': [608.0, 416.0], '1.67': [640.0, 384.0],
+ '1.75': [672.0, 384.0], '2.0': [704.0, 352.0], '2.09': [736.0, 352.0], '2.4': [768.0, 320.0],
+ '2.5': [800.0, 320.0], '2.89': [832.0, 288.0], '3.0': [864.0, 288.0], '3.11': [896.0, 288.0],
+ '3.62': [928.0, 256.0], '3.75': [960.0, 256.0], '3.88': [992.0, 256.0], '4.0': [1024.0, 256.0]
+}
+ASPECT_RATIO_RANDOM_CROP_512 = {
+ '0.42': [320.0, 768.0], '0.5': [352.0, 704.0],
+ '0.57': [384.0, 672.0], '0.68': [416.0, 608.0], '0.78': [448.0, 576.0], '0.88': [480.0, 544.0],
+ '0.94': [480.0, 512.0], '1.0': [512.0, 512.0], '1.07': [512.0, 480.0],
+ '1.13': [544.0, 480.0], '1.29': [576.0, 448.0], '1.46': [608.0, 416.0], '1.75': [672.0, 384.0],
+ '2.0': [704.0, 352.0], '2.4': [768.0, 320.0]
+}
+ASPECT_RATIO_RANDOM_CROP_PROB = [
+ 1, 2,
+ 4, 4, 4, 4,
+ 8, 8, 8,
+ 4, 4, 4, 4,
+ 2, 1
+]
+ASPECT_RATIO_RANDOM_CROP_PROB = np.array(ASPECT_RATIO_RANDOM_CROP_PROB) / sum(ASPECT_RATIO_RANDOM_CROP_PROB)
+
+def get_closest_ratio(height: float, width: float, ratios: dict = ASPECT_RATIO_512):
+ aspect_ratio = height / width
+ closest_ratio = min(ratios.keys(), key=lambda ratio: abs(float(ratio) - aspect_ratio))
+ return ratios[closest_ratio], float(closest_ratio)
+
+def get_image_size_without_loading(path):
+ with Image.open(path) as img:
+ return img.size # (width, height)
+
+class RandomSampler(Sampler[int]):
+ r"""Samples elements randomly. If without replacement, then sample from a shuffled dataset.
+
+ If with replacement, then user can specify :attr:`num_samples` to draw.
+
+ Args:
+ data_source (Dataset): dataset to sample from
+ replacement (bool): samples are drawn on-demand with replacement if ``True``, default=``False``
+ num_samples (int): number of samples to draw, default=`len(dataset)`.
+ generator (Generator): Generator used in sampling.
+ """
+
+ data_source: Sized
+ replacement: bool
+
+ def __init__(self, data_source: Sized, replacement: bool = False,
+ num_samples: Optional[int] = None, generator=None) -> None:
+ self.data_source = data_source
+ self.replacement = replacement
+ self._num_samples = num_samples
+ self.generator = generator
+ self._pos_start = 0
+
+ if not isinstance(self.replacement, bool):
+ raise TypeError(f"replacement should be a boolean value, but got replacement={self.replacement}")
+
+ if not isinstance(self.num_samples, int) or self.num_samples <= 0:
+ raise ValueError(f"num_samples should be a positive integer value, but got num_samples={self.num_samples}")
+
+ @property
+ def num_samples(self) -> int:
+ # dataset size might change at runtime
+ if self._num_samples is None:
+ return len(self.data_source)
+ return self._num_samples
+
+ def __iter__(self) -> Iterator[int]:
+ n = len(self.data_source)
+ if self.generator is None:
+ seed = int(torch.empty((), dtype=torch.int64).random_().item())
+ generator = torch.Generator()
+ generator.manual_seed(seed)
+ else:
+ generator = self.generator
+
+ if self.replacement:
+ for _ in range(self.num_samples // 32):
+ yield from torch.randint(high=n, size=(32,), dtype=torch.int64, generator=generator).tolist()
+ yield from torch.randint(high=n, size=(self.num_samples % 32,), dtype=torch.int64, generator=generator).tolist()
+ else:
+ for _ in range(self.num_samples // n):
+ xx = torch.randperm(n, generator=generator).tolist()
+ if self._pos_start >= n:
+ self._pos_start = 0
+ print("xx top 10", xx[:10], self._pos_start)
+ for idx in range(self._pos_start, n):
+ yield xx[idx]
+ self._pos_start = (self._pos_start + 1) % n
+ self._pos_start = 0
+ yield from torch.randperm(n, generator=generator).tolist()[:self.num_samples % n]
+
+ def __len__(self) -> int:
+ return self.num_samples
+
+class AspectRatioBatchImageSampler(BatchSampler):
+ """A sampler wrapper for grouping images with similar aspect ratio into a same batch.
+
+ Args:
+ sampler (Sampler): Base sampler.
+ dataset (Dataset): Dataset providing data information.
+ batch_size (int): Size of mini-batch.
+ drop_last (bool): If ``True``, the sampler will drop the last batch if
+ its size would be less than ``batch_size``.
+ aspect_ratios (dict): The predefined aspect ratios.
+ """
+ def __init__(
+ self,
+ sampler: Sampler,
+ dataset: Dataset,
+ batch_size: int,
+ train_folder: str = None,
+ aspect_ratios: dict = ASPECT_RATIO_512,
+ drop_last: bool = False,
+ config=None,
+ **kwargs
+ ) -> None:
+ if not isinstance(sampler, Sampler):
+ raise TypeError('sampler should be an instance of ``Sampler``, '
+ f'but got {sampler}')
+ if not isinstance(batch_size, int) or batch_size <= 0:
+ raise ValueError('batch_size should be a positive integer value, '
+ f'but got batch_size={batch_size}')
+ self.sampler = sampler
+ self.dataset = dataset
+ self.train_folder = train_folder
+ self.batch_size = batch_size
+ self.aspect_ratios = aspect_ratios
+ self.drop_last = drop_last
+ self.config = config
+ # buckets for each aspect ratio
+ self._aspect_ratio_buckets = {ratio: [] for ratio in aspect_ratios}
+ # [str(k) for k, v in aspect_ratios]
+ self.current_available_bucket_keys = list(aspect_ratios.keys())
+
+ def __iter__(self):
+ for idx in self.sampler:
+ try:
+ image_dict = self.dataset[idx]
+
+ width, height = image_dict.get("width", None), image_dict.get("height", None)
+ if width is None or height is None:
+ image_id, name = image_dict['file_path'], image_dict['text']
+ if self.train_folder is None:
+ image_dir = image_id
+ else:
+ image_dir = os.path.join(self.train_folder, image_id)
+
+ width, height = get_image_size_without_loading(image_dir)
+
+ ratio = height / width # self.dataset[idx]
+ else:
+ height = int(height)
+ width = int(width)
+ ratio = height / width # self.dataset[idx]
+ except Exception as e:
+ print(e)
+ continue
+ # find the closest aspect ratio
+ closest_ratio = min(self.aspect_ratios.keys(), key=lambda r: abs(float(r) - ratio))
+ if closest_ratio not in self.current_available_bucket_keys:
+ continue
+ bucket = self._aspect_ratio_buckets[closest_ratio]
+ bucket.append(idx)
+ # yield a batch of indices in the same aspect ratio group
+ if len(bucket) == self.batch_size:
+ yield bucket[:]
+ del bucket[:]
+
+class AspectRatioBatchSampler(BatchSampler):
+ """A sampler wrapper for grouping images with similar aspect ratio into a same batch.
+
+ Args:
+ sampler (Sampler): Base sampler.
+ dataset (Dataset): Dataset providing data information.
+ batch_size (int): Size of mini-batch.
+ drop_last (bool): If ``True``, the sampler will drop the last batch if
+ its size would be less than ``batch_size``.
+ aspect_ratios (dict): The predefined aspect ratios.
+ """
+ def __init__(
+ self,
+ sampler: Sampler,
+ dataset: Dataset,
+ batch_size: int,
+ video_folder: str = None,
+ train_data_format: str = "webvid",
+ aspect_ratios: dict = ASPECT_RATIO_512,
+ drop_last: bool = False,
+ config=None,
+ **kwargs
+ ) -> None:
+ if not isinstance(sampler, Sampler):
+ raise TypeError('sampler should be an instance of ``Sampler``, '
+ f'but got {sampler}')
+ if not isinstance(batch_size, int) or batch_size <= 0:
+ raise ValueError('batch_size should be a positive integer value, '
+ f'but got batch_size={batch_size}')
+ self.sampler = sampler
+ self.dataset = dataset
+ self.video_folder = video_folder
+ self.train_data_format = train_data_format
+ self.batch_size = batch_size
+ self.aspect_ratios = aspect_ratios
+ self.drop_last = drop_last
+ self.config = config
+ # buckets for each aspect ratio
+ self._aspect_ratio_buckets = {ratio: [] for ratio in aspect_ratios}
+ # [str(k) for k, v in aspect_ratios]
+ self.current_available_bucket_keys = list(aspect_ratios.keys())
+
+ def __iter__(self):
+ for idx in self.sampler:
+ try:
+ video_dict = self.dataset[idx]
+ width, more = video_dict.get("width", None), video_dict.get("height", None)
+
+ if width is None or height is None:
+ if self.train_data_format == "normal":
+ video_id, name = video_dict['file_path'], video_dict['text']
+ if self.video_folder is None:
+ video_dir = video_id
+ else:
+ video_dir = os.path.join(self.video_folder, video_id)
+ else:
+ videoid, name, page_dir = video_dict['videoid'], video_dict['name'], video_dict['page_dir']
+ video_dir = os.path.join(self.video_folder, f"{videoid}.mp4")
+ cap = cv2.VideoCapture(video_dir)
+
+ # 获取视频尺寸
+ width = int(cap.get(cv2.CAP_PROP_FRAME_WIDTH)) # 浮点数转换为整数
+ height = int(cap.get(cv2.CAP_PROP_FRAME_HEIGHT)) # 浮点数转换为整数
+
+ ratio = height / width # self.dataset[idx]
+ else:
+ height = int(height)
+ width = int(width)
+ ratio = height / width # self.dataset[idx]
+ except Exception as e:
+ print(e)
+ continue
+ # find the closest aspect ratio
+ closest_ratio = min(self.aspect_ratios.keys(), key=lambda r: abs(float(r) - ratio))
+ if closest_ratio not in self.current_available_bucket_keys:
+ continue
+ bucket = self._aspect_ratio_buckets[closest_ratio]
+ bucket.append(idx)
+ # yield a batch of indices in the same aspect ratio group
+ if len(bucket) == self.batch_size:
+ yield bucket[:]
+ del bucket[:]
+
+class AspectRatioBatchImageVideoSampler(BatchSampler):
+ """A sampler wrapper for grouping images with similar aspect ratio into a same batch.
+
+ Args:
+ sampler (Sampler): Base sampler.
+ dataset (Dataset): Dataset providing data information.
+ batch_size (int): Size of mini-batch.
+ drop_last (bool): If ``True``, the sampler will drop the last batch if
+ its size would be less than ``batch_size``.
+ aspect_ratios (dict): The predefined aspect ratios.
+ """
+
+ def __init__(self,
+ sampler: Sampler,
+ dataset: Dataset,
+ batch_size: int,
+ train_folder: str = None,
+ aspect_ratios: dict = ASPECT_RATIO_512,
+ drop_last: bool = False
+ ) -> None:
+ if not isinstance(sampler, Sampler):
+ raise TypeError('sampler should be an instance of ``Sampler``, '
+ f'but got {sampler}')
+ if not isinstance(batch_size, int) or batch_size <= 0:
+ raise ValueError('batch_size should be a positive integer value, '
+ f'but got batch_size={batch_size}')
+ self.sampler = sampler
+ self.dataset = dataset
+ self.train_folder = train_folder
+ self.batch_size = batch_size
+ self.aspect_ratios = aspect_ratios
+ self.drop_last = drop_last
+
+ # buckets for each aspect ratio
+ self.current_available_bucket_keys = list(aspect_ratios.keys())
+ self.bucket = {
+ 'image':{ratio: [] for ratio in aspect_ratios},
+ 'video':{ratio: [] for ratio in aspect_ratios}
+ }
+
+ def __iter__(self):
+ for idx in self.sampler:
+ content_type = self.dataset[idx].get('type', 'image')
+ if content_type == 'image':
+ try:
+ image_dict = self.dataset[idx]
+
+ width, height = image_dict.get("width", None), image_dict.get("height", None)
+ if width is None or height is None:
+ image_id, name = image_dict['file_path'], image_dict['text']
+ if self.train_folder is None:
+ image_dir = image_id
+ else:
+ image_dir = os.path.join(self.train_folder, image_id)
+
+ width, height = get_image_size_without_loading(image_dir)
+
+ ratio = height / width # self.dataset[idx]
+ else:
+ height = int(height)
+ width = int(width)
+ ratio = height / width # self.dataset[idx]
+ except Exception as e:
+ print(e)
+ continue
+ # find the closest aspect ratio
+ closest_ratio = min(self.aspect_ratios.keys(), key=lambda r: abs(float(r) - ratio))
+ if closest_ratio not in self.current_available_bucket_keys:
+ continue
+ bucket = self.bucket['image'][closest_ratio]
+ bucket.append(idx)
+ # yield a batch of indices in the same aspect ratio group
+ if len(bucket) == self.batch_size:
+ yield bucket[:]
+ del bucket[:]
+ else:
+ try:
+ video_dict = self.dataset[idx]
+ width, height = video_dict.get("width", None), video_dict.get("height", None)
+
+ if width is None or height is None:
+ video_id, name = video_dict['file_path'], video_dict['text']
+ if self.train_folder is None:
+ video_dir = video_id
+ else:
+ video_dir = os.path.join(self.train_folder, video_id)
+ cap = cv2.VideoCapture(video_dir)
+
+ # 获取视频尺寸
+ width = int(cap.get(cv2.CAP_PROP_FRAME_WIDTH)) # 浮点数转换为整数
+ height = int(cap.get(cv2.CAP_PROP_FRAME_HEIGHT)) # 浮点数转换为整数
+
+ ratio = height / width # self.dataset[idx]
+ else:
+ height = int(height)
+ width = int(width)
+ ratio = height / width # self.dataset[idx]
+ except Exception as e:
+ print(e)
+ continue
+ # find the closest aspect ratio
+ closest_ratio = min(self.aspect_ratios.keys(), key=lambda r: abs(float(r) - ratio))
+ if closest_ratio not in self.current_available_bucket_keys:
+ continue
+ bucket = self.bucket['video'][closest_ratio]
+ bucket.append(idx)
+ # yield a batch of indices in the same aspect ratio group
+ if len(bucket) == self.batch_size:
+ yield bucket[:]
+ del bucket[:]
\ No newline at end of file
diff --git a/cogvideox/data/dataset_image.py b/cogvideox/data/dataset_image.py
new file mode 100644
index 0000000..098d49a
--- /dev/null
+++ b/cogvideox/data/dataset_image.py
@@ -0,0 +1,76 @@
+import json
+import os
+import random
+
+import numpy as np
+import torch
+import torchvision.transforms as transforms
+from PIL import Image
+from torch.utils.data.dataset import Dataset
+
+
+class CC15M(Dataset):
+ def __init__(
+ self,
+ json_path,
+ video_folder=None,
+ resolution=512,
+ enable_bucket=False,
+ ):
+ print(f"loading annotations from {json_path} ...")
+ self.dataset = json.load(open(json_path, 'r'))
+ self.length = len(self.dataset)
+ print(f"data scale: {self.length}")
+
+ self.enable_bucket = enable_bucket
+ self.video_folder = video_folder
+
+ resolution = tuple(resolution) if not isinstance(resolution, int) else (resolution, resolution)
+ self.pixel_transforms = transforms.Compose([
+ transforms.Resize(resolution[0]),
+ transforms.CenterCrop(resolution),
+ transforms.ToTensor(),
+ transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
+ ])
+
+ def get_batch(self, idx):
+ video_dict = self.dataset[idx]
+ video_id, name = video_dict['file_path'], video_dict['text']
+
+ if self.video_folder is None:
+ video_dir = video_id
+ else:
+ video_dir = os.path.join(self.video_folder, video_id)
+
+ pixel_values = Image.open(video_dir).convert("RGB")
+ return pixel_values, name
+
+ def __len__(self):
+ return self.length
+
+ def __getitem__(self, idx):
+ while True:
+ try:
+ pixel_values, name = self.get_batch(idx)
+ break
+ except Exception as e:
+ print(e)
+ idx = random.randint(0, self.length-1)
+
+ if not self.enable_bucket:
+ pixel_values = self.pixel_transforms(pixel_values)
+ else:
+ pixel_values = np.array(pixel_values)
+
+ sample = dict(pixel_values=pixel_values, text=name)
+ return sample
+
+if __name__ == "__main__":
+ dataset = CC15M(
+ csv_path="/mnt_wg/zhoumo.xjq/CCUtils/cc15m_add_index.json",
+ resolution=512,
+ )
+
+ dataloader = torch.utils.data.DataLoader(dataset, batch_size=4, num_workers=0,)
+ for idx, batch in enumerate(dataloader):
+ print(batch["pixel_values"].shape, len(batch["text"]))
\ No newline at end of file
diff --git a/cogvideox/data/dataset_image_video.py b/cogvideox/data/dataset_image_video.py
new file mode 100644
index 0000000..8d0bb58
--- /dev/null
+++ b/cogvideox/data/dataset_image_video.py
@@ -0,0 +1,324 @@
+import csv
+import io
+import json
+import math
+import os
+import random
+from threading import Thread
+
+import albumentations
+import cv2
+import gc
+import numpy as np
+import torch
+import torchvision.transforms as transforms
+
+from func_timeout import func_timeout, FunctionTimedOut
+from decord import VideoReader
+from PIL import Image
+from torch.utils.data import BatchSampler, Sampler
+from torch.utils.data.dataset import Dataset
+from contextlib import contextmanager
+
+VIDEO_READER_TIMEOUT = 20
+
+def get_random_mask(shape):
+ f, c, h, w = shape
+
+ if f != 1:
+ mask_index = np.random.choice([0, 1, 2, 3, 4], p = [0.05, 0.3, 0.3, 0.3, 0.05]) # np.random.randint(0, 5)
+ else:
+ mask_index = np.random.choice([0, 1], p = [0.2, 0.8]) # np.random.randint(0, 2)
+ mask = torch.zeros((f, 1, h, w), dtype=torch.uint8)
+
+ if mask_index == 0:
+ center_x = torch.randint(0, w, (1,)).item()
+ center_y = torch.randint(0, h, (1,)).item()
+ block_size_x = torch.randint(w // 4, w // 4 * 3, (1,)).item() # 方块的宽度范围
+ block_size_y = torch.randint(h // 4, h // 4 * 3, (1,)).item() # 方块的高度范围
+
+ start_x = max(center_x - block_size_x // 2, 0)
+ end_x = min(center_x + block_size_x // 2, w)
+ start_y = max(center_y - block_size_y // 2, 0)
+ end_y = min(center_y + block_size_y // 2, h)
+ mask[:, :, start_y:end_y, start_x:end_x] = 1
+ elif mask_index == 1:
+ mask[:, :, :, :] = 1
+ elif mask_index == 2:
+ mask_frame_index = np.random.randint(1, 5)
+ mask[mask_frame_index:, :, :, :] = 1
+ elif mask_index == 3:
+ mask_frame_index = np.random.randint(1, 5)
+ mask[mask_frame_index:-mask_frame_index, :, :, :] = 1
+ elif mask_index == 4:
+ center_x = torch.randint(0, w, (1,)).item()
+ center_y = torch.randint(0, h, (1,)).item()
+ block_size_x = torch.randint(w // 4, w // 4 * 3, (1,)).item() # 方块的宽度范围
+ block_size_y = torch.randint(h // 4, h // 4 * 3, (1,)).item() # 方块的高度范围
+
+ start_x = max(center_x - block_size_x // 2, 0)
+ end_x = min(center_x + block_size_x // 2, w)
+ start_y = max(center_y - block_size_y // 2, 0)
+ end_y = min(center_y + block_size_y // 2, h)
+
+ mask_frame_before = np.random.randint(0, f // 2)
+ mask_frame_after = np.random.randint(f // 2, f)
+ mask[mask_frame_before:mask_frame_after, :, start_y:end_y, start_x:end_x] = 1
+ else:
+ raise ValueError(f"The mask_index {mask_index} is not define")
+ return mask
+
+class ImageVideoSampler(BatchSampler):
+ """A sampler wrapper for grouping images with similar aspect ratio into a same batch.
+
+ Args:
+ sampler (Sampler): Base sampler.
+ dataset (Dataset): Dataset providing data information.
+ batch_size (int): Size of mini-batch.
+ drop_last (bool): If ``True``, the sampler will drop the last batch if
+ its size would be less than ``batch_size``.
+ aspect_ratios (dict): The predefined aspect ratios.
+ """
+
+ def __init__(self,
+ sampler: Sampler,
+ dataset: Dataset,
+ batch_size: int,
+ drop_last: bool = False
+ ) -> None:
+ if not isinstance(sampler, Sampler):
+ raise TypeError('sampler should be an instance of ``Sampler``, '
+ f'but got {sampler}')
+ if not isinstance(batch_size, int) or batch_size <= 0:
+ raise ValueError('batch_size should be a positive integer value, '
+ f'but got batch_size={batch_size}')
+ self.sampler = sampler
+ self.dataset = dataset
+ self.batch_size = batch_size
+ self.drop_last = drop_last
+
+ # buckets for each aspect ratio
+ self.bucket = {'image':[], 'video':[]}
+
+ def __iter__(self):
+ for idx in self.sampler:
+ content_type = self.dataset.dataset[idx].get('type', 'image')
+ self.bucket[content_type].append(idx)
+
+ # yield a batch of indices in the same aspect ratio group
+ if len(self.bucket['video']) == self.batch_size:
+ bucket = self.bucket['video']
+ yield bucket[:]
+ del bucket[:]
+ elif len(self.bucket['image']) == self.batch_size:
+ bucket = self.bucket['image']
+ yield bucket[:]
+ del bucket[:]
+
+@contextmanager
+def VideoReader_contextmanager(*args, **kwargs):
+ vr = VideoReader(*args, **kwargs)
+ try:
+ yield vr
+ finally:
+ del vr
+ gc.collect()
+
+def get_video_reader_batch(video_reader, batch_index):
+ frames = video_reader.get_batch(batch_index).asnumpy()
+ return frames
+
+def resize_frame(frame, target_short_side):
+ h, w, _ = frame.shape
+ if h < w:
+ if target_short_side > h:
+ return frame
+ new_h = target_short_side
+ new_w = int(target_short_side * w / h)
+ else:
+ if target_short_side > w:
+ return frame
+ new_w = target_short_side
+ new_h = int(target_short_side * h / w)
+
+ resized_frame = cv2.resize(frame, (new_w, new_h))
+ return resized_frame
+
+class ImageVideoDataset(Dataset):
+ def __init__(
+ self,
+ ann_path, data_root=None,
+ video_sample_size=512, video_sample_stride=4, video_sample_n_frames=16,
+ image_sample_size=512,
+ video_repeat=0,
+ text_drop_ratio=-1,
+ enable_bucket=False,
+ video_length_drop_start=0.1,
+ video_length_drop_end=0.9,
+ enable_inpaint=False,
+ ):
+ # Loading annotations from files
+ print(f"loading annotations from {ann_path} ...")
+ if ann_path.endswith('.csv'):
+ with open(ann_path, 'r') as csvfile:
+ dataset = list(csv.DictReader(csvfile))
+ elif ann_path.endswith('.json'):
+ dataset = json.load(open(ann_path))
+
+ self.data_root = data_root
+
+ # It's used to balance num of images and videos.
+ self.dataset = []
+ for data in dataset:
+ if data.get('type', 'image') != 'video':
+ self.dataset.append(data)
+ if video_repeat > 0:
+ for _ in range(video_repeat):
+ for data in dataset:
+ if data.get('type', 'image') == 'video':
+ self.dataset.append(data)
+ del dataset
+
+ self.length = len(self.dataset)
+ print(f"data scale: {self.length}")
+ # TODO: enable bucket training
+ self.enable_bucket = enable_bucket
+ self.text_drop_ratio = text_drop_ratio
+ self.enable_inpaint = enable_inpaint
+
+ self.video_length_drop_start = video_length_drop_start
+ self.video_length_drop_end = video_length_drop_end
+
+ # Video params
+ self.video_sample_stride = video_sample_stride
+ self.video_sample_n_frames = video_sample_n_frames
+ self.video_sample_size = tuple(video_sample_size) if not isinstance(video_sample_size, int) else (video_sample_size, video_sample_size)
+ self.video_transforms = transforms.Compose(
+ [
+ transforms.Resize(min(self.video_sample_size)),
+ transforms.CenterCrop(self.video_sample_size),
+ transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
+ ]
+ )
+
+ # Image params
+ self.image_sample_size = tuple(image_sample_size) if not isinstance(image_sample_size, int) else (image_sample_size, image_sample_size)
+ self.image_transforms = transforms.Compose([
+ transforms.Resize(min(self.image_sample_size)),
+ transforms.CenterCrop(self.image_sample_size),
+ transforms.ToTensor(),
+ transforms.Normalize([0.5, 0.5, 0.5],[0.5, 0.5, 0.5])
+ ])
+
+ self.larger_side_of_image_and_video = max(min(self.image_sample_size), min(self.video_sample_size))
+
+ def get_batch(self, idx):
+ data_info = self.dataset[idx % len(self.dataset)]
+
+ if data_info.get('type', 'image')=='video':
+ video_id, text = data_info['file_path'], data_info['text']
+
+ if self.data_root is None:
+ video_dir = video_id
+ else:
+ video_dir = os.path.join(self.data_root, video_id)
+
+ with VideoReader_contextmanager(video_dir, num_threads=2) as video_reader:
+ min_sample_n_frames = min(
+ self.video_sample_n_frames,
+ int(len(video_reader) * (self.video_length_drop_end - self.video_length_drop_start) // self.video_sample_stride)
+ )
+ if min_sample_n_frames == 0:
+ raise ValueError(f"No Frames in video.")
+
+ video_length = int(self.video_length_drop_end * len(video_reader))
+ clip_length = min(video_length, (min_sample_n_frames - 1) * self.video_sample_stride + 1)
+ start_idx = random.randint(int(self.video_length_drop_start * video_length), video_length - clip_length) if video_length != clip_length else 0
+ batch_index = np.linspace(start_idx, start_idx + clip_length - 1, min_sample_n_frames, dtype=int)
+
+ try:
+ sample_args = (video_reader, batch_index)
+ pixel_values = func_timeout(
+ VIDEO_READER_TIMEOUT, get_video_reader_batch, args=sample_args
+ )
+ resized_frames = []
+ for i in range(len(pixel_values)):
+ frame = pixel_values[i]
+ resized_frame = resize_frame(frame, self.larger_side_of_image_and_video)
+ resized_frames.append(resized_frame)
+ pixel_values = np.array(resized_frames)
+ except FunctionTimedOut:
+ raise ValueError(f"Read {idx} timeout.")
+ except Exception as e:
+ raise ValueError(f"Failed to extract frames from video. Error is {e}.")
+
+ if not self.enable_bucket:
+ pixel_values = torch.from_numpy(pixel_values).permute(0, 3, 1, 2).contiguous()
+ pixel_values = pixel_values / 255.
+ del video_reader
+ else:
+ pixel_values = pixel_values
+
+ if not self.enable_bucket:
+ pixel_values = self.video_transforms(pixel_values)
+
+ # Random use no text generation
+ if random.random() < self.text_drop_ratio:
+ text = ''
+ return pixel_values, text, 'video'
+ else:
+ image_path, text = data_info['file_path'], data_info['text']
+ if self.data_root is not None:
+ image_path = os.path.join(self.data_root, image_path)
+ image = Image.open(image_path).convert('RGB')
+ if not self.enable_bucket:
+ image = self.image_transforms(image).unsqueeze(0)
+ else:
+ image = np.expand_dims(np.array(image), 0)
+ if random.random() < self.text_drop_ratio:
+ text = ''
+ return image, text, 'image'
+
+ def __len__(self):
+ return self.length
+
+ def __getitem__(self, idx):
+ data_info = self.dataset[idx % len(self.dataset)]
+ data_type = data_info.get('type', 'image')
+ while True:
+ sample = {}
+ try:
+ data_info_local = self.dataset[idx % len(self.dataset)]
+ data_type_local = data_info_local.get('type', 'image')
+ if data_type_local != data_type:
+ raise ValueError("data_type_local != data_type")
+
+ pixel_values, name, data_type = self.get_batch(idx)
+ sample["pixel_values"] = pixel_values
+ sample["text"] = name
+ sample["data_type"] = data_type
+ sample["idx"] = idx
+
+ if len(sample) > 0:
+ break
+ except Exception as e:
+ print(e, self.dataset[idx % len(self.dataset)])
+ idx = random.randint(0, self.length-1)
+
+ if self.enable_inpaint and not self.enable_bucket:
+ mask = get_random_mask(pixel_values.size())
+ mask_pixel_values = pixel_values * (1 - mask) + torch.ones_like(pixel_values) * -1 * mask
+ sample["mask_pixel_values"] = mask_pixel_values
+ sample["mask"] = mask
+
+ clip_pixel_values = sample["pixel_values"][0].permute(1, 2, 0).contiguous()
+ clip_pixel_values = (clip_pixel_values * 0.5 + 0.5) * 255
+ sample["clip_pixel_values"] = clip_pixel_values
+
+ ref_pixel_values = sample["pixel_values"][0].unsqueeze(0)
+ if (mask == 1).all():
+ ref_pixel_values = torch.ones_like(ref_pixel_values) * -1
+ sample["ref_pixel_values"] = ref_pixel_values
+
+ return sample
+
diff --git a/cogvideox/data/dataset_video.py b/cogvideox/data/dataset_video.py
new file mode 100644
index 0000000..c78367d
--- /dev/null
+++ b/cogvideox/data/dataset_video.py
@@ -0,0 +1,262 @@
+import csv
+import gc
+import io
+import json
+import math
+import os
+import random
+from contextlib import contextmanager
+from threading import Thread
+
+import albumentations
+import cv2
+import numpy as np
+import torch
+import torchvision.transforms as transforms
+from decord import VideoReader
+from einops import rearrange
+from func_timeout import FunctionTimedOut, func_timeout
+from PIL import Image
+from torch.utils.data import BatchSampler, Sampler
+from torch.utils.data.dataset import Dataset
+
+VIDEO_READER_TIMEOUT = 20
+
+def get_random_mask(shape):
+ f, c, h, w = shape
+
+ mask_index = np.random.randint(0, 4)
+ mask = torch.zeros((f, 1, h, w), dtype=torch.uint8)
+ if mask_index == 0:
+ mask[1:, :, :, :] = 1
+ elif mask_index == 1:
+ mask_frame_index = 1
+ mask[mask_frame_index:-mask_frame_index, :, :, :] = 1
+ elif mask_index == 2:
+ center_x = torch.randint(0, w, (1,)).item()
+ center_y = torch.randint(0, h, (1,)).item()
+ block_size_x = torch.randint(w // 4, w // 4 * 3, (1,)).item() # 方块的宽度范围
+ block_size_y = torch.randint(h // 4, h // 4 * 3, (1,)).item() # 方块的高度范围
+
+ start_x = max(center_x - block_size_x // 2, 0)
+ end_x = min(center_x + block_size_x // 2, w)
+ start_y = max(center_y - block_size_y // 2, 0)
+ end_y = min(center_y + block_size_y // 2, h)
+ mask[:, :, start_y:end_y, start_x:end_x] = 1
+ elif mask_index == 3:
+ center_x = torch.randint(0, w, (1,)).item()
+ center_y = torch.randint(0, h, (1,)).item()
+ block_size_x = torch.randint(w // 4, w // 4 * 3, (1,)).item() # 方块的宽度范围
+ block_size_y = torch.randint(h // 4, h // 4 * 3, (1,)).item() # 方块的高度范围
+
+ start_x = max(center_x - block_size_x // 2, 0)
+ end_x = min(center_x + block_size_x // 2, w)
+ start_y = max(center_y - block_size_y // 2, 0)
+ end_y = min(center_y + block_size_y // 2, h)
+
+ mask_frame_before = np.random.randint(0, f // 2)
+ mask_frame_after = np.random.randint(f // 2, f)
+ mask[mask_frame_before:mask_frame_after, :, start_y:end_y, start_x:end_x] = 1
+ else:
+ raise ValueError(f"The mask_index {mask_index} is not define")
+ return mask
+
+
+@contextmanager
+def VideoReader_contextmanager(*args, **kwargs):
+ vr = VideoReader(*args, **kwargs)
+ try:
+ yield vr
+ finally:
+ del vr
+ gc.collect()
+
+
+def get_video_reader_batch(video_reader, batch_index):
+ frames = video_reader.get_batch(batch_index).asnumpy()
+ return frames
+
+
+class WebVid10M(Dataset):
+ def __init__(
+ self,
+ csv_path, video_folder,
+ sample_size=256, sample_stride=4, sample_n_frames=16,
+ enable_bucket=False, enable_inpaint=False, is_image=False,
+ ):
+ print(f"loading annotations from {csv_path} ...")
+ with open(csv_path, 'r') as csvfile:
+ self.dataset = list(csv.DictReader(csvfile))
+ self.length = len(self.dataset)
+ print(f"data scale: {self.length}")
+
+ self.video_folder = video_folder
+ self.sample_stride = sample_stride
+ self.sample_n_frames = sample_n_frames
+ self.enable_bucket = enable_bucket
+ self.enable_inpaint = enable_inpaint
+ self.is_image = is_image
+
+ sample_size = tuple(sample_size) if not isinstance(sample_size, int) else (sample_size, sample_size)
+ self.pixel_transforms = transforms.Compose([
+ transforms.Resize(sample_size[0]),
+ transforms.CenterCrop(sample_size),
+ transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
+ ])
+
+ def get_batch(self, idx):
+ video_dict = self.dataset[idx]
+ videoid, name, page_dir = video_dict['videoid'], video_dict['name'], video_dict['page_dir']
+
+ video_dir = os.path.join(self.video_folder, f"{videoid}.mp4")
+ video_reader = VideoReader(video_dir)
+ video_length = len(video_reader)
+
+ if not self.is_image:
+ clip_length = min(video_length, (self.sample_n_frames - 1) * self.sample_stride + 1)
+ start_idx = random.randint(0, video_length - clip_length)
+ batch_index = np.linspace(start_idx, start_idx + clip_length - 1, self.sample_n_frames, dtype=int)
+ else:
+ batch_index = [random.randint(0, video_length - 1)]
+
+ if not self.enable_bucket:
+ pixel_values = torch.from_numpy(video_reader.get_batch(batch_index).asnumpy()).permute(0, 3, 1, 2).contiguous()
+ pixel_values = pixel_values / 255.
+ del video_reader
+ else:
+ pixel_values = video_reader.get_batch(batch_index).asnumpy()
+
+ if self.is_image:
+ pixel_values = pixel_values[0]
+ return pixel_values, name
+
+ def __len__(self):
+ return self.length
+
+ def __getitem__(self, idx):
+ while True:
+ try:
+ pixel_values, name = self.get_batch(idx)
+ break
+
+ except Exception as e:
+ print("Error info:", e)
+ idx = random.randint(0, self.length-1)
+
+ if not self.enable_bucket:
+ pixel_values = self.pixel_transforms(pixel_values)
+ if self.enable_inpaint:
+ mask = get_random_mask(pixel_values.size())
+ mask_pixel_values = pixel_values * (1 - mask) + torch.ones_like(pixel_values) * -1 * mask
+ sample = dict(pixel_values=pixel_values, mask_pixel_values=mask_pixel_values, mask=mask, text=name)
+ else:
+ sample = dict(pixel_values=pixel_values, text=name)
+ return sample
+
+
+class VideoDataset(Dataset):
+ def __init__(
+ self,
+ json_path, video_folder=None,
+ sample_size=256, sample_stride=4, sample_n_frames=16,
+ enable_bucket=False, enable_inpaint=False
+ ):
+ print(f"loading annotations from {json_path} ...")
+ self.dataset = json.load(open(json_path, 'r'))
+ self.length = len(self.dataset)
+ print(f"data scale: {self.length}")
+
+ self.video_folder = video_folder
+ self.sample_stride = sample_stride
+ self.sample_n_frames = sample_n_frames
+ self.enable_bucket = enable_bucket
+ self.enable_inpaint = enable_inpaint
+
+ sample_size = tuple(sample_size) if not isinstance(sample_size, int) else (sample_size, sample_size)
+ self.pixel_transforms = transforms.Compose(
+ [
+ transforms.Resize(sample_size[0]),
+ transforms.CenterCrop(sample_size),
+ transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
+ ]
+ )
+
+ def get_batch(self, idx):
+ video_dict = self.dataset[idx]
+ video_id, name = video_dict['file_path'], video_dict['text']
+
+ if self.video_folder is None:
+ video_dir = video_id
+ else:
+ video_dir = os.path.join(self.video_folder, video_id)
+
+ with VideoReader_contextmanager(video_dir, num_threads=2) as video_reader:
+ video_length = len(video_reader)
+
+ clip_length = min(video_length, (self.sample_n_frames - 1) * self.sample_stride + 1)
+ start_idx = random.randint(0, video_length - clip_length)
+ batch_index = np.linspace(start_idx, start_idx + clip_length - 1, self.sample_n_frames, dtype=int)
+
+ try:
+ sample_args = (video_reader, batch_index)
+ pixel_values = func_timeout(
+ VIDEO_READER_TIMEOUT, get_video_reader_batch, args=sample_args
+ )
+ except FunctionTimedOut:
+ raise ValueError(f"Read {idx} timeout.")
+ except Exception as e:
+ raise ValueError(f"Failed to extract frames from video. Error is {e}.")
+
+ if not self.enable_bucket:
+ pixel_values = torch.from_numpy(pixel_values).permute(0, 3, 1, 2).contiguous()
+ pixel_values = pixel_values / 255.
+ del video_reader
+ else:
+ pixel_values = pixel_values
+
+ return pixel_values, name
+
+ def __len__(self):
+ return self.length
+
+ def __getitem__(self, idx):
+ while True:
+ try:
+ pixel_values, name = self.get_batch(idx)
+ break
+
+ except Exception as e:
+ print("Error info:", e)
+ idx = random.randint(0, self.length-1)
+
+ if not self.enable_bucket:
+ pixel_values = self.pixel_transforms(pixel_values)
+ if self.enable_inpaint:
+ mask = get_random_mask(pixel_values.size())
+ mask_pixel_values = pixel_values * (1 - mask) + torch.ones_like(pixel_values) * -1 * mask
+ sample = dict(pixel_values=pixel_values, mask_pixel_values=mask_pixel_values, mask=mask, text=name)
+ else:
+ sample = dict(pixel_values=pixel_values, text=name)
+ return sample
+
+
+if __name__ == "__main__":
+ if 1:
+ dataset = VideoDataset(
+ json_path="/home/zhoumo.xjq/disk3/datasets/webvidval/results_2M_val.json",
+ sample_size=256,
+ sample_stride=4, sample_n_frames=16,
+ )
+
+ if 0:
+ dataset = WebVid10M(
+ csv_path="/mnt/petrelfs/guoyuwei/projects/datasets/webvid/results_2M_val.csv",
+ video_folder="/mnt/petrelfs/guoyuwei/projects/datasets/webvid/2M_val",
+ sample_size=256,
+ sample_stride=4, sample_n_frames=16,
+ is_image=False,
+ )
+
+ dataloader = torch.utils.data.DataLoader(dataset, batch_size=4, num_workers=0,)
+ for idx, batch in enumerate(dataloader):
+ print(batch["pixel_values"].shape, len(batch["text"]))
\ No newline at end of file
diff --git a/cogvideox/models/autoencoder_magvit.py b/cogvideox/models/autoencoder_magvit.py
new file mode 100644
index 0000000..9c2b906
--- /dev/null
+++ b/cogvideox/models/autoencoder_magvit.py
@@ -0,0 +1,1296 @@
+# Copyright 2024 The CogVideoX team, Tsinghua University & ZhipuAI and The HuggingFace Team.
+# All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import Optional, Tuple, Union
+
+import numpy as np
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+from diffusers.configuration_utils import ConfigMixin, register_to_config
+from diffusers.loaders.single_file_model import FromOriginalModelMixin
+from diffusers.utils import logging
+from diffusers.utils.accelerate_utils import apply_forward_hook
+from diffusers.models.activations import get_activation
+from diffusers.models.downsampling import CogVideoXDownsample3D
+from diffusers.models.modeling_outputs import AutoencoderKLOutput
+from diffusers.models.modeling_utils import ModelMixin
+from diffusers.models.upsampling import CogVideoXUpsample3D
+from diffusers.models.autoencoders.vae import DecoderOutput, DiagonalGaussianDistribution
+
+
+logger = logging.get_logger(__name__) # pylint: disable=invalid-name
+
+
+class CogVideoXSafeConv3d(nn.Conv3d):
+ r"""
+ A 3D convolution layer that splits the input tensor into smaller parts to avoid OOM in CogVideoX Model.
+ """
+
+ def forward(self, input: torch.Tensor) -> torch.Tensor:
+ memory_count = torch.prod(torch.tensor(input.shape)).item() * 2 / 1024**3
+
+ # Set to 2GB, suitable for CuDNN
+ if memory_count > 2:
+ kernel_size = self.kernel_size[0]
+ part_num = int(memory_count / 2) + 1
+ input_chunks = torch.chunk(input, part_num, dim=2)
+
+ if kernel_size > 1:
+ input_chunks = [input_chunks[0]] + [
+ torch.cat((input_chunks[i - 1][:, :, -kernel_size + 1 :], input_chunks[i]), dim=2)
+ for i in range(1, len(input_chunks))
+ ]
+
+ output_chunks = []
+ for input_chunk in input_chunks:
+ output_chunks.append(super().forward(input_chunk))
+ output = torch.cat(output_chunks, dim=2)
+ return output
+ else:
+ return super().forward(input)
+
+
+class CogVideoXCausalConv3d(nn.Module):
+ r"""A 3D causal convolution layer that pads the input tensor to ensure causality in CogVideoX Model.
+
+ Args:
+ in_channels (`int`): Number of channels in the input tensor.
+ out_channels (`int`): Number of output channels produced by the convolution.
+ kernel_size (`int` or `Tuple[int, int, int]`): Kernel size of the convolutional kernel.
+ stride (`int`, defaults to `1`): Stride of the convolution.
+ dilation (`int`, defaults to `1`): Dilation rate of the convolution.
+ pad_mode (`str`, defaults to `"constant"`): Padding mode.
+ """
+
+ def __init__(
+ self,
+ in_channels: int,
+ out_channels: int,
+ kernel_size: Union[int, Tuple[int, int, int]],
+ stride: int = 1,
+ dilation: int = 1,
+ pad_mode: str = "constant",
+ ):
+ super().__init__()
+
+ if isinstance(kernel_size, int):
+ kernel_size = (kernel_size,) * 3
+
+ time_kernel_size, height_kernel_size, width_kernel_size = kernel_size
+
+ self.pad_mode = pad_mode
+ time_pad = dilation * (time_kernel_size - 1) + (1 - stride)
+ height_pad = height_kernel_size // 2
+ width_pad = width_kernel_size // 2
+
+ self.height_pad = height_pad
+ self.width_pad = width_pad
+ self.time_pad = time_pad
+ self.time_causal_padding = (width_pad, width_pad, height_pad, height_pad, time_pad, 0)
+
+ self.temporal_dim = 2
+ self.time_kernel_size = time_kernel_size
+
+ stride = (stride, 1, 1)
+ dilation = (dilation, 1, 1)
+ self.conv = CogVideoXSafeConv3d(
+ in_channels=in_channels,
+ out_channels=out_channels,
+ kernel_size=kernel_size,
+ stride=stride,
+ dilation=dilation,
+ )
+
+ self.conv_cache = None
+
+ def fake_context_parallel_forward(self, inputs: torch.Tensor) -> torch.Tensor:
+ kernel_size = self.time_kernel_size
+ if kernel_size > 1:
+ cached_inputs = (
+ [self.conv_cache] if self.conv_cache is not None else [inputs[:, :, :1]] * (kernel_size - 1)
+ )
+ inputs = torch.cat(cached_inputs + [inputs], dim=2)
+ return inputs
+
+ def _clear_fake_context_parallel_cache(self):
+ del self.conv_cache
+ self.conv_cache = None
+
+ def forward(self, inputs: torch.Tensor) -> torch.Tensor:
+ inputs = self.fake_context_parallel_forward(inputs)
+
+ self._clear_fake_context_parallel_cache()
+ # Note: we could move these to the cpu for a lower maximum memory usage but its only a few
+ # hundred megabytes and so let's not do it for now
+ self.conv_cache = inputs[:, :, -self.time_kernel_size + 1 :].clone()
+
+ padding_2d = (self.width_pad, self.width_pad, self.height_pad, self.height_pad)
+ inputs = F.pad(inputs, padding_2d, mode="constant", value=0)
+
+ output = self.conv(inputs)
+ return output
+
+
+class CogVideoXSpatialNorm3D(nn.Module):
+ r"""
+ Spatially conditioned normalization as defined in https://arxiv.org/abs/2209.09002. This implementation is specific
+ to 3D-video like data.
+
+ CogVideoXSafeConv3d is used instead of nn.Conv3d to avoid OOM in CogVideoX Model.
+
+ Args:
+ f_channels (`int`):
+ The number of channels for input to group normalization layer, and output of the spatial norm layer.
+ zq_channels (`int`):
+ The number of channels for the quantized vector as described in the paper.
+ groups (`int`):
+ Number of groups to separate the channels into for group normalization.
+ """
+
+ def __init__(
+ self,
+ f_channels: int,
+ zq_channels: int,
+ groups: int = 32,
+ ):
+ super().__init__()
+ self.norm_layer = nn.GroupNorm(num_channels=f_channels, num_groups=groups, eps=1e-6, affine=True)
+ self.conv_y = CogVideoXCausalConv3d(zq_channels, f_channels, kernel_size=1, stride=1)
+ self.conv_b = CogVideoXCausalConv3d(zq_channels, f_channels, kernel_size=1, stride=1)
+
+ def forward(self, f: torch.Tensor, zq: torch.Tensor) -> torch.Tensor:
+ if f.shape[2] > 1 and f.shape[2] % 2 == 1:
+ f_first, f_rest = f[:, :, :1], f[:, :, 1:]
+ f_first_size, f_rest_size = f_first.shape[-3:], f_rest.shape[-3:]
+ z_first, z_rest = zq[:, :, :1], zq[:, :, 1:]
+ z_first = F.interpolate(z_first, size=f_first_size)
+ z_rest = F.interpolate(z_rest, size=f_rest_size)
+ zq = torch.cat([z_first, z_rest], dim=2)
+ else:
+ zq = F.interpolate(zq, size=f.shape[-3:])
+
+ norm_f = self.norm_layer(f)
+ new_f = norm_f * self.conv_y(zq) + self.conv_b(zq)
+ return new_f
+
+
+class CogVideoXResnetBlock3D(nn.Module):
+ r"""
+ A 3D ResNet block used in the CogVideoX model.
+
+ Args:
+ in_channels (`int`):
+ Number of input channels.
+ out_channels (`int`, *optional*):
+ Number of output channels. If None, defaults to `in_channels`.
+ dropout (`float`, defaults to `0.0`):
+ Dropout rate.
+ temb_channels (`int`, defaults to `512`):
+ Number of time embedding channels.
+ groups (`int`, defaults to `32`):
+ Number of groups to separate the channels into for group normalization.
+ eps (`float`, defaults to `1e-6`):
+ Epsilon value for normalization layers.
+ non_linearity (`str`, defaults to `"swish"`):
+ Activation function to use.
+ conv_shortcut (bool, defaults to `False`):
+ Whether or not to use a convolution shortcut.
+ spatial_norm_dim (`int`, *optional*):
+ The dimension to use for spatial norm if it is to be used instead of group norm.
+ pad_mode (str, defaults to `"first"`):
+ Padding mode.
+ """
+
+ def __init__(
+ self,
+ in_channels: int,
+ out_channels: Optional[int] = None,
+ dropout: float = 0.0,
+ temb_channels: int = 512,
+ groups: int = 32,
+ eps: float = 1e-6,
+ non_linearity: str = "swish",
+ conv_shortcut: bool = False,
+ spatial_norm_dim: Optional[int] = None,
+ pad_mode: str = "first",
+ ):
+ super().__init__()
+
+ out_channels = out_channels or in_channels
+
+ self.in_channels = in_channels
+ self.out_channels = out_channels
+ self.nonlinearity = get_activation(non_linearity)
+ self.use_conv_shortcut = conv_shortcut
+
+ if spatial_norm_dim is None:
+ self.norm1 = nn.GroupNorm(num_channels=in_channels, num_groups=groups, eps=eps)
+ self.norm2 = nn.GroupNorm(num_channels=out_channels, num_groups=groups, eps=eps)
+ else:
+ self.norm1 = CogVideoXSpatialNorm3D(
+ f_channels=in_channels,
+ zq_channels=spatial_norm_dim,
+ groups=groups,
+ )
+ self.norm2 = CogVideoXSpatialNorm3D(
+ f_channels=out_channels,
+ zq_channels=spatial_norm_dim,
+ groups=groups,
+ )
+
+ self.conv1 = CogVideoXCausalConv3d(
+ in_channels=in_channels, out_channels=out_channels, kernel_size=3, pad_mode=pad_mode
+ )
+
+ if temb_channels > 0:
+ self.temb_proj = nn.Linear(in_features=temb_channels, out_features=out_channels)
+
+ self.dropout = nn.Dropout(dropout)
+ self.conv2 = CogVideoXCausalConv3d(
+ in_channels=out_channels, out_channels=out_channels, kernel_size=3, pad_mode=pad_mode
+ )
+
+ if self.in_channels != self.out_channels:
+ if self.use_conv_shortcut:
+ self.conv_shortcut = CogVideoXCausalConv3d(
+ in_channels=in_channels, out_channels=out_channels, kernel_size=3, pad_mode=pad_mode
+ )
+ else:
+ self.conv_shortcut = CogVideoXSafeConv3d(
+ in_channels=in_channels, out_channels=out_channels, kernel_size=1, stride=1, padding=0
+ )
+
+ def forward(
+ self,
+ inputs: torch.Tensor,
+ temb: Optional[torch.Tensor] = None,
+ zq: Optional[torch.Tensor] = None,
+ ) -> torch.Tensor:
+ hidden_states = inputs
+
+ if zq is not None:
+ hidden_states = self.norm1(hidden_states, zq)
+ else:
+ hidden_states = self.norm1(hidden_states)
+
+ hidden_states = self.nonlinearity(hidden_states)
+ hidden_states = self.conv1(hidden_states)
+
+ if temb is not None:
+ hidden_states = hidden_states + self.temb_proj(self.nonlinearity(temb))[:, :, None, None, None]
+
+ if zq is not None:
+ hidden_states = self.norm2(hidden_states, zq)
+ else:
+ hidden_states = self.norm2(hidden_states)
+
+ hidden_states = self.nonlinearity(hidden_states)
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.conv2(hidden_states)
+
+ if self.in_channels != self.out_channels:
+ inputs = self.conv_shortcut(inputs)
+
+ hidden_states = hidden_states + inputs
+ return hidden_states
+
+
+class CogVideoXDownBlock3D(nn.Module):
+ r"""
+ A downsampling block used in the CogVideoX model.
+
+ Args:
+ in_channels (`int`):
+ Number of input channels.
+ out_channels (`int`, *optional*):
+ Number of output channels. If None, defaults to `in_channels`.
+ temb_channels (`int`, defaults to `512`):
+ Number of time embedding channels.
+ num_layers (`int`, defaults to `1`):
+ Number of resnet layers.
+ dropout (`float`, defaults to `0.0`):
+ Dropout rate.
+ resnet_eps (`float`, defaults to `1e-6`):
+ Epsilon value for normalization layers.
+ resnet_act_fn (`str`, defaults to `"swish"`):
+ Activation function to use.
+ resnet_groups (`int`, defaults to `32`):
+ Number of groups to separate the channels into for group normalization.
+ add_downsample (`bool`, defaults to `True`):
+ Whether or not to use a downsampling layer. If not used, output dimension would be same as input dimension.
+ compress_time (`bool`, defaults to `False`):
+ Whether or not to downsample across temporal dimension.
+ pad_mode (str, defaults to `"first"`):
+ Padding mode.
+ """
+
+ _supports_gradient_checkpointing = True
+
+ def __init__(
+ self,
+ in_channels: int,
+ out_channels: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ resnet_eps: float = 1e-6,
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ add_downsample: bool = True,
+ downsample_padding: int = 0,
+ compress_time: bool = False,
+ pad_mode: str = "first",
+ ):
+ super().__init__()
+
+ resnets = []
+ for i in range(num_layers):
+ in_channel = in_channels if i == 0 else out_channels
+ resnets.append(
+ CogVideoXResnetBlock3D(
+ in_channels=in_channel,
+ out_channels=out_channels,
+ dropout=dropout,
+ temb_channels=temb_channels,
+ groups=resnet_groups,
+ eps=resnet_eps,
+ non_linearity=resnet_act_fn,
+ pad_mode=pad_mode,
+ )
+ )
+
+ self.resnets = nn.ModuleList(resnets)
+ self.downsamplers = None
+
+ if add_downsample:
+ self.downsamplers = nn.ModuleList(
+ [
+ CogVideoXDownsample3D(
+ out_channels, out_channels, padding=downsample_padding, compress_time=compress_time
+ )
+ ]
+ )
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ temb: Optional[torch.Tensor] = None,
+ zq: Optional[torch.Tensor] = None,
+ ) -> torch.Tensor:
+ for resnet in self.resnets:
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module):
+ def create_forward(*inputs):
+ return module(*inputs)
+
+ return create_forward
+
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(resnet), hidden_states, temb, zq
+ )
+ else:
+ hidden_states = resnet(hidden_states, temb, zq)
+
+ if self.downsamplers is not None:
+ for downsampler in self.downsamplers:
+ hidden_states = downsampler(hidden_states)
+
+ return hidden_states
+
+
+class CogVideoXMidBlock3D(nn.Module):
+ r"""
+ A middle block used in the CogVideoX model.
+
+ Args:
+ in_channels (`int`):
+ Number of input channels.
+ temb_channels (`int`, defaults to `512`):
+ Number of time embedding channels.
+ dropout (`float`, defaults to `0.0`):
+ Dropout rate.
+ num_layers (`int`, defaults to `1`):
+ Number of resnet layers.
+ resnet_eps (`float`, defaults to `1e-6`):
+ Epsilon value for normalization layers.
+ resnet_act_fn (`str`, defaults to `"swish"`):
+ Activation function to use.
+ resnet_groups (`int`, defaults to `32`):
+ Number of groups to separate the channels into for group normalization.
+ spatial_norm_dim (`int`, *optional*):
+ The dimension to use for spatial norm if it is to be used instead of group norm.
+ pad_mode (str, defaults to `"first"`):
+ Padding mode.
+ """
+
+ _supports_gradient_checkpointing = True
+
+ def __init__(
+ self,
+ in_channels: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ resnet_eps: float = 1e-6,
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ spatial_norm_dim: Optional[int] = None,
+ pad_mode: str = "first",
+ ):
+ super().__init__()
+
+ resnets = []
+ for _ in range(num_layers):
+ resnets.append(
+ CogVideoXResnetBlock3D(
+ in_channels=in_channels,
+ out_channels=in_channels,
+ dropout=dropout,
+ temb_channels=temb_channels,
+ groups=resnet_groups,
+ eps=resnet_eps,
+ spatial_norm_dim=spatial_norm_dim,
+ non_linearity=resnet_act_fn,
+ pad_mode=pad_mode,
+ )
+ )
+ self.resnets = nn.ModuleList(resnets)
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ temb: Optional[torch.Tensor] = None,
+ zq: Optional[torch.Tensor] = None,
+ ) -> torch.Tensor:
+ for resnet in self.resnets:
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module):
+ def create_forward(*inputs):
+ return module(*inputs)
+
+ return create_forward
+
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(resnet), hidden_states, temb, zq
+ )
+ else:
+ hidden_states = resnet(hidden_states, temb, zq)
+
+ return hidden_states
+
+
+class CogVideoXUpBlock3D(nn.Module):
+ r"""
+ An upsampling block used in the CogVideoX model.
+
+ Args:
+ in_channels (`int`):
+ Number of input channels.
+ out_channels (`int`, *optional*):
+ Number of output channels. If None, defaults to `in_channels`.
+ temb_channels (`int`, defaults to `512`):
+ Number of time embedding channels.
+ dropout (`float`, defaults to `0.0`):
+ Dropout rate.
+ num_layers (`int`, defaults to `1`):
+ Number of resnet layers.
+ resnet_eps (`float`, defaults to `1e-6`):
+ Epsilon value for normalization layers.
+ resnet_act_fn (`str`, defaults to `"swish"`):
+ Activation function to use.
+ resnet_groups (`int`, defaults to `32`):
+ Number of groups to separate the channels into for group normalization.
+ spatial_norm_dim (`int`, defaults to `16`):
+ The dimension to use for spatial norm if it is to be used instead of group norm.
+ add_upsample (`bool`, defaults to `True`):
+ Whether or not to use a upsampling layer. If not used, output dimension would be same as input dimension.
+ compress_time (`bool`, defaults to `False`):
+ Whether or not to downsample across temporal dimension.
+ pad_mode (str, defaults to `"first"`):
+ Padding mode.
+ """
+
+ def __init__(
+ self,
+ in_channels: int,
+ out_channels: int,
+ temb_channels: int,
+ dropout: float = 0.0,
+ num_layers: int = 1,
+ resnet_eps: float = 1e-6,
+ resnet_act_fn: str = "swish",
+ resnet_groups: int = 32,
+ spatial_norm_dim: int = 16,
+ add_upsample: bool = True,
+ upsample_padding: int = 1,
+ compress_time: bool = False,
+ pad_mode: str = "first",
+ ):
+ super().__init__()
+
+ resnets = []
+ for i in range(num_layers):
+ in_channel = in_channels if i == 0 else out_channels
+ resnets.append(
+ CogVideoXResnetBlock3D(
+ in_channels=in_channel,
+ out_channels=out_channels,
+ dropout=dropout,
+ temb_channels=temb_channels,
+ groups=resnet_groups,
+ eps=resnet_eps,
+ non_linearity=resnet_act_fn,
+ spatial_norm_dim=spatial_norm_dim,
+ pad_mode=pad_mode,
+ )
+ )
+
+ self.resnets = nn.ModuleList(resnets)
+ self.upsamplers = None
+
+ if add_upsample:
+ self.upsamplers = nn.ModuleList(
+ [
+ CogVideoXUpsample3D(
+ out_channels, out_channels, padding=upsample_padding, compress_time=compress_time
+ )
+ ]
+ )
+
+ self.gradient_checkpointing = False
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ temb: Optional[torch.Tensor] = None,
+ zq: Optional[torch.Tensor] = None,
+ ) -> torch.Tensor:
+ r"""Forward method of the `CogVideoXUpBlock3D` class."""
+ for resnet in self.resnets:
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module):
+ def create_forward(*inputs):
+ return module(*inputs)
+
+ return create_forward
+
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(resnet), hidden_states, temb, zq
+ )
+ else:
+ hidden_states = resnet(hidden_states, temb, zq)
+
+ if self.upsamplers is not None:
+ for upsampler in self.upsamplers:
+ hidden_states = upsampler(hidden_states)
+
+ return hidden_states
+
+
+class CogVideoXEncoder3D(nn.Module):
+ r"""
+ The `CogVideoXEncoder3D` layer of a variational autoencoder that encodes its input into a latent representation.
+
+ Args:
+ in_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ out_channels (`int`, *optional*, defaults to 3):
+ The number of output channels.
+ down_block_types (`Tuple[str, ...]`, *optional*, defaults to `("DownEncoderBlock2D",)`):
+ The types of down blocks to use. See `~diffusers.models.unet_2d_blocks.get_down_block` for available
+ options.
+ block_out_channels (`Tuple[int, ...]`, *optional*, defaults to `(64,)`):
+ The number of output channels for each block.
+ act_fn (`str`, *optional*, defaults to `"silu"`):
+ The activation function to use. See `~diffusers.models.activations.get_activation` for available options.
+ layers_per_block (`int`, *optional*, defaults to 2):
+ The number of layers per block.
+ norm_num_groups (`int`, *optional*, defaults to 32):
+ The number of groups for normalization.
+ """
+
+ _supports_gradient_checkpointing = True
+
+ def __init__(
+ self,
+ in_channels: int = 3,
+ out_channels: int = 16,
+ down_block_types: Tuple[str, ...] = (
+ "CogVideoXDownBlock3D",
+ "CogVideoXDownBlock3D",
+ "CogVideoXDownBlock3D",
+ "CogVideoXDownBlock3D",
+ ),
+ block_out_channels: Tuple[int, ...] = (128, 256, 256, 512),
+ layers_per_block: int = 3,
+ act_fn: str = "silu",
+ norm_eps: float = 1e-6,
+ norm_num_groups: int = 32,
+ dropout: float = 0.0,
+ pad_mode: str = "first",
+ temporal_compression_ratio: float = 4,
+ ):
+ super().__init__()
+
+ # log2 of temporal_compress_times
+ temporal_compress_level = int(np.log2(temporal_compression_ratio))
+
+ self.conv_in = CogVideoXCausalConv3d(in_channels, block_out_channels[0], kernel_size=3, pad_mode=pad_mode)
+ self.down_blocks = nn.ModuleList([])
+
+ # down blocks
+ output_channel = block_out_channels[0]
+ for i, down_block_type in enumerate(down_block_types):
+ input_channel = output_channel
+ output_channel = block_out_channels[i]
+ is_final_block = i == len(block_out_channels) - 1
+ compress_time = i < temporal_compress_level
+
+ if down_block_type == "CogVideoXDownBlock3D":
+ down_block = CogVideoXDownBlock3D(
+ in_channels=input_channel,
+ out_channels=output_channel,
+ temb_channels=0,
+ dropout=dropout,
+ num_layers=layers_per_block,
+ resnet_eps=norm_eps,
+ resnet_act_fn=act_fn,
+ resnet_groups=norm_num_groups,
+ add_downsample=not is_final_block,
+ compress_time=compress_time,
+ )
+ else:
+ raise ValueError("Invalid `down_block_type` encountered. Must be `CogVideoXDownBlock3D`")
+
+ self.down_blocks.append(down_block)
+
+ # mid block
+ self.mid_block = CogVideoXMidBlock3D(
+ in_channels=block_out_channels[-1],
+ temb_channels=0,
+ dropout=dropout,
+ num_layers=2,
+ resnet_eps=norm_eps,
+ resnet_act_fn=act_fn,
+ resnet_groups=norm_num_groups,
+ pad_mode=pad_mode,
+ )
+
+ self.norm_out = nn.GroupNorm(norm_num_groups, block_out_channels[-1], eps=1e-6)
+ self.conv_act = nn.SiLU()
+ self.conv_out = CogVideoXCausalConv3d(
+ block_out_channels[-1], 2 * out_channels, kernel_size=3, pad_mode=pad_mode
+ )
+
+ self.gradient_checkpointing = False
+
+ def forward(self, sample: torch.Tensor, temb: Optional[torch.Tensor] = None) -> torch.Tensor:
+ r"""The forward method of the `CogVideoXEncoder3D` class."""
+ hidden_states = self.conv_in(sample)
+
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module):
+ def custom_forward(*inputs):
+ return module(*inputs)
+
+ return custom_forward
+
+ # 1. Down
+ for down_block in self.down_blocks:
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(down_block), hidden_states, temb, None
+ )
+
+ # 2. Mid
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(self.mid_block), hidden_states, temb, None
+ )
+ else:
+ # 1. Down
+ for down_block in self.down_blocks:
+ hidden_states = down_block(hidden_states, temb, None)
+
+ # 2. Mid
+ hidden_states = self.mid_block(hidden_states, temb, None)
+
+ # 3. Post-process
+ hidden_states = self.norm_out(hidden_states)
+ hidden_states = self.conv_act(hidden_states)
+ hidden_states = self.conv_out(hidden_states)
+ return hidden_states
+
+
+class CogVideoXDecoder3D(nn.Module):
+ r"""
+ The `CogVideoXDecoder3D` layer of a variational autoencoder that decodes its latent representation into an output
+ sample.
+
+ Args:
+ in_channels (`int`, *optional*, defaults to 3):
+ The number of input channels.
+ out_channels (`int`, *optional*, defaults to 3):
+ The number of output channels.
+ up_block_types (`Tuple[str, ...]`, *optional*, defaults to `("UpDecoderBlock2D",)`):
+ The types of up blocks to use. See `~diffusers.models.unet_2d_blocks.get_up_block` for available options.
+ block_out_channels (`Tuple[int, ...]`, *optional*, defaults to `(64,)`):
+ The number of output channels for each block.
+ act_fn (`str`, *optional*, defaults to `"silu"`):
+ The activation function to use. See `~diffusers.models.activations.get_activation` for available options.
+ layers_per_block (`int`, *optional*, defaults to 2):
+ The number of layers per block.
+ norm_num_groups (`int`, *optional*, defaults to 32):
+ The number of groups for normalization.
+ """
+
+ _supports_gradient_checkpointing = True
+
+ def __init__(
+ self,
+ in_channels: int = 16,
+ out_channels: int = 3,
+ up_block_types: Tuple[str, ...] = (
+ "CogVideoXUpBlock3D",
+ "CogVideoXUpBlock3D",
+ "CogVideoXUpBlock3D",
+ "CogVideoXUpBlock3D",
+ ),
+ block_out_channels: Tuple[int, ...] = (128, 256, 256, 512),
+ layers_per_block: int = 3,
+ act_fn: str = "silu",
+ norm_eps: float = 1e-6,
+ norm_num_groups: int = 32,
+ dropout: float = 0.0,
+ pad_mode: str = "first",
+ temporal_compression_ratio: float = 4,
+ ):
+ super().__init__()
+
+ reversed_block_out_channels = list(reversed(block_out_channels))
+
+ self.conv_in = CogVideoXCausalConv3d(
+ in_channels, reversed_block_out_channels[0], kernel_size=3, pad_mode=pad_mode
+ )
+
+ # mid block
+ self.mid_block = CogVideoXMidBlock3D(
+ in_channels=reversed_block_out_channels[0],
+ temb_channels=0,
+ num_layers=2,
+ resnet_eps=norm_eps,
+ resnet_act_fn=act_fn,
+ resnet_groups=norm_num_groups,
+ spatial_norm_dim=in_channels,
+ pad_mode=pad_mode,
+ )
+
+ # up blocks
+ self.up_blocks = nn.ModuleList([])
+
+ output_channel = reversed_block_out_channels[0]
+ temporal_compress_level = int(np.log2(temporal_compression_ratio))
+
+ for i, up_block_type in enumerate(up_block_types):
+ prev_output_channel = output_channel
+ output_channel = reversed_block_out_channels[i]
+ is_final_block = i == len(block_out_channels) - 1
+ compress_time = i < temporal_compress_level
+
+ if up_block_type == "CogVideoXUpBlock3D":
+ up_block = CogVideoXUpBlock3D(
+ in_channels=prev_output_channel,
+ out_channels=output_channel,
+ temb_channels=0,
+ dropout=dropout,
+ num_layers=layers_per_block + 1,
+ resnet_eps=norm_eps,
+ resnet_act_fn=act_fn,
+ resnet_groups=norm_num_groups,
+ spatial_norm_dim=in_channels,
+ add_upsample=not is_final_block,
+ compress_time=compress_time,
+ pad_mode=pad_mode,
+ )
+ prev_output_channel = output_channel
+ else:
+ raise ValueError("Invalid `up_block_type` encountered. Must be `CogVideoXUpBlock3D`")
+
+ self.up_blocks.append(up_block)
+
+ self.norm_out = CogVideoXSpatialNorm3D(reversed_block_out_channels[-1], in_channels, groups=norm_num_groups)
+ self.conv_act = nn.SiLU()
+ self.conv_out = CogVideoXCausalConv3d(
+ reversed_block_out_channels[-1], out_channels, kernel_size=3, pad_mode=pad_mode
+ )
+
+ self.gradient_checkpointing = False
+
+ def forward(self, sample: torch.Tensor, temb: Optional[torch.Tensor] = None) -> torch.Tensor:
+ r"""The forward method of the `CogVideoXDecoder3D` class."""
+ hidden_states = self.conv_in(sample)
+
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module):
+ def custom_forward(*inputs):
+ return module(*inputs)
+
+ return custom_forward
+
+ # 1. Mid
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(self.mid_block), hidden_states, temb, sample
+ )
+
+ # 2. Up
+ for up_block in self.up_blocks:
+ hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(up_block), hidden_states, temb, sample
+ )
+ else:
+ # 1. Mid
+ hidden_states = self.mid_block(hidden_states, temb, sample)
+
+ # 2. Up
+ for up_block in self.up_blocks:
+ hidden_states = up_block(hidden_states, temb, sample)
+
+ # 3. Post-process
+ hidden_states = self.norm_out(hidden_states, sample)
+ hidden_states = self.conv_act(hidden_states)
+ hidden_states = self.conv_out(hidden_states)
+ return hidden_states
+
+
+class AutoencoderKLCogVideoX(ModelMixin, ConfigMixin, FromOriginalModelMixin):
+ r"""
+ A VAE model with KL loss for encoding images into latents and decoding latent representations into images. Used in
+ [CogVideoX](https://github.com/THUDM/CogVideo).
+
+ This model inherits from [`ModelMixin`]. Check the superclass documentation for it's generic methods implemented
+ for all models (such as downloading or saving).
+
+ Parameters:
+ in_channels (int, *optional*, defaults to 3): Number of channels in the input image.
+ out_channels (int, *optional*, defaults to 3): Number of channels in the output.
+ down_block_types (`Tuple[str]`, *optional*, defaults to `("DownEncoderBlock2D",)`):
+ Tuple of downsample block types.
+ up_block_types (`Tuple[str]`, *optional*, defaults to `("UpDecoderBlock2D",)`):
+ Tuple of upsample block types.
+ block_out_channels (`Tuple[int]`, *optional*, defaults to `(64,)`):
+ Tuple of block output channels.
+ act_fn (`str`, *optional*, defaults to `"silu"`): The activation function to use.
+ sample_size (`int`, *optional*, defaults to `32`): Sample input size.
+ scaling_factor (`float`, *optional*, defaults to `1.15258426`):
+ The component-wise standard deviation of the trained latent space computed using the first batch of the
+ training set. This is used to scale the latent space to have unit variance when training the diffusion
+ model. The latents are scaled with the formula `z = z * scaling_factor` before being passed to the
+ diffusion model. When decoding, the latents are scaled back to the original scale with the formula: `z = 1
+ / scaling_factor * z`. For more details, refer to sections 4.3.2 and D.1 of the [High-Resolution Image
+ Synthesis with Latent Diffusion Models](https://arxiv.org/abs/2112.10752) paper.
+ force_upcast (`bool`, *optional*, default to `True`):
+ If enabled it will force the VAE to run in float32 for high image resolution pipelines, such as SD-XL. VAE
+ can be fine-tuned / trained to a lower range without loosing too much precision in which case
+ `force_upcast` can be set to `False` - see: https://huggingface.co/madebyollin/sdxl-vae-fp16-fix
+ """
+
+ _supports_gradient_checkpointing = True
+ _no_split_modules = ["CogVideoXResnetBlock3D"]
+
+ @register_to_config
+ def __init__(
+ self,
+ in_channels: int = 3,
+ out_channels: int = 3,
+ down_block_types: Tuple[str] = (
+ "CogVideoXDownBlock3D",
+ "CogVideoXDownBlock3D",
+ "CogVideoXDownBlock3D",
+ "CogVideoXDownBlock3D",
+ ),
+ up_block_types: Tuple[str] = (
+ "CogVideoXUpBlock3D",
+ "CogVideoXUpBlock3D",
+ "CogVideoXUpBlock3D",
+ "CogVideoXUpBlock3D",
+ ),
+ block_out_channels: Tuple[int] = (128, 256, 256, 512),
+ latent_channels: int = 16,
+ layers_per_block: int = 3,
+ act_fn: str = "silu",
+ norm_eps: float = 1e-6,
+ norm_num_groups: int = 32,
+ temporal_compression_ratio: float = 4,
+ sample_height: int = 480,
+ sample_width: int = 720,
+ scaling_factor: float = 1.15258426,
+ shift_factor: Optional[float] = None,
+ latents_mean: Optional[Tuple[float]] = None,
+ latents_std: Optional[Tuple[float]] = None,
+ force_upcast: float = True,
+ use_quant_conv: bool = False,
+ use_post_quant_conv: bool = False,
+ ):
+ super().__init__()
+
+ self.encoder = CogVideoXEncoder3D(
+ in_channels=in_channels,
+ out_channels=latent_channels,
+ down_block_types=down_block_types,
+ block_out_channels=block_out_channels,
+ layers_per_block=layers_per_block,
+ act_fn=act_fn,
+ norm_eps=norm_eps,
+ norm_num_groups=norm_num_groups,
+ temporal_compression_ratio=temporal_compression_ratio,
+ )
+ self.decoder = CogVideoXDecoder3D(
+ in_channels=latent_channels,
+ out_channels=out_channels,
+ up_block_types=up_block_types,
+ block_out_channels=block_out_channels,
+ layers_per_block=layers_per_block,
+ act_fn=act_fn,
+ norm_eps=norm_eps,
+ norm_num_groups=norm_num_groups,
+ temporal_compression_ratio=temporal_compression_ratio,
+ )
+ self.quant_conv = CogVideoXSafeConv3d(2 * out_channels, 2 * out_channels, 1) if use_quant_conv else None
+ self.post_quant_conv = CogVideoXSafeConv3d(out_channels, out_channels, 1) if use_post_quant_conv else None
+
+ self.use_slicing = False
+ self.use_tiling = False
+
+ # Can be increased to decode more latent frames at once, but comes at a reasonable memory cost and it is not
+ # recommended because the temporal parts of the VAE, here, are tricky to understand.
+ # If you decode X latent frames together, the number of output frames is:
+ # (X + (2 conv cache) + (2 time upscale_1) + (4 time upscale_2) - (2 causal conv downscale)) => X + 6 frames
+ #
+ # Example with num_latent_frames_batch_size = 2:
+ # - 12 latent frames: (0, 1), (2, 3), (4, 5), (6, 7), (8, 9), (10, 11) are processed together
+ # => (12 // 2 frame slices) * ((2 num_latent_frames_batch_size) + (2 conv cache) + (2 time upscale_1) + (4 time upscale_2) - (2 causal conv downscale))
+ # => 6 * 8 = 48 frames
+ # - 13 latent frames: (0, 1, 2) (special case), (3, 4), (5, 6), (7, 8), (9, 10), (11, 12) are processed together
+ # => (1 frame slice) * ((3 num_latent_frames_batch_size) + (2 conv cache) + (2 time upscale_1) + (4 time upscale_2) - (2 causal conv downscale)) +
+ # ((13 - 3) // 2) * ((2 num_latent_frames_batch_size) + (2 conv cache) + (2 time upscale_1) + (4 time upscale_2) - (2 causal conv downscale))
+ # => 1 * 9 + 5 * 8 = 49 frames
+ # It has been implemented this way so as to not have "magic values" in the code base that would be hard to explain. Note that
+ # setting it to anything other than 2 would give poor results because the VAE hasn't been trained to be adaptive with different
+ # number of temporal frames.
+ self.num_latent_frames_batch_size = 2
+
+ # We make the minimum height and width of sample for tiling half that of the generally supported
+ self.tile_sample_min_height = sample_height // 2
+ self.tile_sample_min_width = sample_width // 2
+ self.tile_latent_min_height = int(
+ self.tile_sample_min_height / (2 ** (len(self.config.block_out_channels) - 1))
+ )
+ self.tile_latent_min_width = int(self.tile_sample_min_width / (2 ** (len(self.config.block_out_channels) - 1)))
+
+ # These are experimental overlap factors that were chosen based on experimentation and seem to work best for
+ # 720x480 (WxH) resolution. The above resolution is the strongly recommended generation resolution in CogVideoX
+ # and so the tiling implementation has only been tested on those specific resolutions.
+ self.tile_overlap_factor_height = 1 / 6
+ self.tile_overlap_factor_width = 1 / 5
+
+ def _set_gradient_checkpointing(self, module, value=False):
+ if isinstance(module, (CogVideoXEncoder3D, CogVideoXDecoder3D)):
+ module.gradient_checkpointing = value
+
+ def _clear_fake_context_parallel_cache(self):
+ for name, module in self.named_modules():
+ if isinstance(module, CogVideoXCausalConv3d):
+ logger.debug(f"Clearing fake Context Parallel cache for layer: {name}")
+ module._clear_fake_context_parallel_cache()
+
+ def enable_tiling(
+ self,
+ tile_sample_min_height: Optional[int] = None,
+ tile_sample_min_width: Optional[int] = None,
+ tile_overlap_factor_height: Optional[float] = None,
+ tile_overlap_factor_width: Optional[float] = None,
+ ) -> None:
+ r"""
+ Enable tiled VAE decoding. When this option is enabled, the VAE will split the input tensor into tiles to
+ compute decoding and encoding in several steps. This is useful for saving a large amount of memory and to allow
+ processing larger images.
+
+ Args:
+ tile_sample_min_height (`int`, *optional*):
+ The minimum height required for a sample to be separated into tiles across the height dimension.
+ tile_sample_min_width (`int`, *optional*):
+ The minimum width required for a sample to be separated into tiles across the width dimension.
+ tile_overlap_factor_height (`int`, *optional*):
+ The minimum amount of overlap between two consecutive vertical tiles. This is to ensure that there are
+ no tiling artifacts produced across the height dimension. Must be between 0 and 1. Setting a higher
+ value might cause more tiles to be processed leading to slow down of the decoding process.
+ tile_overlap_factor_width (`int`, *optional*):
+ The minimum amount of overlap between two consecutive horizontal tiles. This is to ensure that there
+ are no tiling artifacts produced across the width dimension. Must be between 0 and 1. Setting a higher
+ value might cause more tiles to be processed leading to slow down of the decoding process.
+ """
+ self.use_tiling = True
+ self.tile_sample_min_height = tile_sample_min_height or self.tile_sample_min_height
+ self.tile_sample_min_width = tile_sample_min_width or self.tile_sample_min_width
+ self.tile_latent_min_height = int(
+ self.tile_sample_min_height / (2 ** (len(self.config.block_out_channels) - 1))
+ )
+ self.tile_latent_min_width = int(self.tile_sample_min_width / (2 ** (len(self.config.block_out_channels) - 1)))
+ self.tile_overlap_factor_height = tile_overlap_factor_height or self.tile_overlap_factor_height
+ self.tile_overlap_factor_width = tile_overlap_factor_width or self.tile_overlap_factor_width
+
+ def disable_tiling(self) -> None:
+ r"""
+ Disable tiled VAE decoding. If `enable_tiling` was previously enabled, this method will go back to computing
+ decoding in one step.
+ """
+ self.use_tiling = False
+
+ def enable_slicing(self) -> None:
+ r"""
+ Enable sliced VAE decoding. When this option is enabled, the VAE will split the input tensor in slices to
+ compute decoding in several steps. This is useful to save some memory and allow larger batch sizes.
+ """
+ self.use_slicing = True
+
+ def disable_slicing(self) -> None:
+ r"""
+ Disable sliced VAE decoding. If `enable_slicing` was previously enabled, this method will go back to computing
+ decoding in one step.
+ """
+ self.use_slicing = False
+
+ @apply_forward_hook
+ def encode(
+ self, x: torch.Tensor, return_dict: bool = True
+ ) -> Union[AutoencoderKLOutput, Tuple[DiagonalGaussianDistribution]]:
+ """
+ Encode a batch of images into latents.
+
+ Args:
+ x (`torch.Tensor`): Input batch of images.
+ return_dict (`bool`, *optional*, defaults to `True`):
+ Whether to return a [`~models.autoencoder_kl.AutoencoderKLOutput`] instead of a plain tuple.
+
+ Returns:
+ The latent representations of the encoded images. If `return_dict` is True, a
+ [`~models.autoencoder_kl.AutoencoderKLOutput`] is returned, otherwise a plain `tuple` is returned.
+ """
+ batch_size, num_channels, num_frames, height, width = x.shape
+ if num_frames == 1:
+ h = self.encoder(x)
+ if self.quant_conv is not None:
+ h = self.quant_conv(h)
+ posterior = DiagonalGaussianDistribution(h)
+ else:
+ frame_batch_size = 4
+ h = []
+ for i in range(num_frames // frame_batch_size):
+ remaining_frames = num_frames % frame_batch_size
+ start_frame = frame_batch_size * i + (0 if i == 0 else remaining_frames)
+ end_frame = frame_batch_size * (i + 1) + remaining_frames
+ z_intermediate = x[:, :, start_frame:end_frame]
+ z_intermediate = self.encoder(z_intermediate)
+ if self.quant_conv is not None:
+ z_intermediate = self.quant_conv(z_intermediate)
+ h.append(z_intermediate)
+ self._clear_fake_context_parallel_cache()
+ h = torch.cat(h, dim=2)
+ posterior = DiagonalGaussianDistribution(h)
+ if not return_dict:
+ return (posterior,)
+ return AutoencoderKLOutput(latent_dist=posterior)
+
+ def _decode(self, z: torch.Tensor, return_dict: bool = True) -> Union[DecoderOutput, torch.Tensor]:
+ batch_size, num_channels, num_frames, height, width = z.shape
+
+ if self.use_tiling and (width > self.tile_latent_min_width or height > self.tile_latent_min_height):
+ return self.tiled_decode(z, return_dict=return_dict)
+
+ if num_frames == 1:
+ dec = []
+ z_intermediate = z
+ if self.post_quant_conv is not None:
+ z_intermediate = self.post_quant_conv(z_intermediate)
+ z_intermediate = self.decoder(z_intermediate)
+ dec.append(z_intermediate)
+ else:
+ frame_batch_size = self.num_latent_frames_batch_size
+ dec = []
+ for i in range(num_frames // frame_batch_size):
+ remaining_frames = num_frames % frame_batch_size
+ start_frame = frame_batch_size * i + (0 if i == 0 else remaining_frames)
+ end_frame = frame_batch_size * (i + 1) + remaining_frames
+ z_intermediate = z[:, :, start_frame:end_frame]
+ if self.post_quant_conv is not None:
+ z_intermediate = self.post_quant_conv(z_intermediate)
+ z_intermediate = self.decoder(z_intermediate)
+ dec.append(z_intermediate)
+
+ self._clear_fake_context_parallel_cache()
+ dec = torch.cat(dec, dim=2)
+
+ if not return_dict:
+ return (dec,)
+
+ return DecoderOutput(sample=dec)
+
+ @apply_forward_hook
+ def decode(self, z: torch.Tensor, return_dict: bool = True) -> Union[DecoderOutput, torch.Tensor]:
+ """
+ Decode a batch of images.
+
+ Args:
+ z (`torch.Tensor`): Input batch of latent vectors.
+ return_dict (`bool`, *optional*, defaults to `True`):
+ Whether to return a [`~models.vae.DecoderOutput`] instead of a plain tuple.
+
+ Returns:
+ [`~models.vae.DecoderOutput`] or `tuple`:
+ If return_dict is True, a [`~models.vae.DecoderOutput`] is returned, otherwise a plain `tuple` is
+ returned.
+ """
+ if self.use_slicing and z.shape[0] > 1:
+ decoded_slices = [self._decode(z_slice).sample for z_slice in z.split(1)]
+ decoded = torch.cat(decoded_slices)
+ else:
+ decoded = self._decode(z).sample
+
+ if not return_dict:
+ return (decoded,)
+ return DecoderOutput(sample=decoded)
+
+ def blend_v(self, a: torch.Tensor, b: torch.Tensor, blend_extent: int) -> torch.Tensor:
+ blend_extent = min(a.shape[3], b.shape[3], blend_extent)
+ for y in range(blend_extent):
+ b[:, :, :, y, :] = a[:, :, :, -blend_extent + y, :] * (1 - y / blend_extent) + b[:, :, :, y, :] * (
+ y / blend_extent
+ )
+ return b
+
+ def blend_h(self, a: torch.Tensor, b: torch.Tensor, blend_extent: int) -> torch.Tensor:
+ blend_extent = min(a.shape[4], b.shape[4], blend_extent)
+ for x in range(blend_extent):
+ b[:, :, :, :, x] = a[:, :, :, :, -blend_extent + x] * (1 - x / blend_extent) + b[:, :, :, :, x] * (
+ x / blend_extent
+ )
+ return b
+
+ def tiled_decode(self, z: torch.Tensor, return_dict: bool = True) -> Union[DecoderOutput, torch.Tensor]:
+ r"""
+ Decode a batch of images using a tiled decoder.
+
+ Args:
+ z (`torch.Tensor`): Input batch of latent vectors.
+ return_dict (`bool`, *optional*, defaults to `True`):
+ Whether or not to return a [`~models.vae.DecoderOutput`] instead of a plain tuple.
+
+ Returns:
+ [`~models.vae.DecoderOutput`] or `tuple`:
+ If return_dict is True, a [`~models.vae.DecoderOutput`] is returned, otherwise a plain `tuple` is
+ returned.
+ """
+ # Rough memory assessment:
+ # - In CogVideoX-2B, there are a total of 24 CausalConv3d layers.
+ # - The biggest intermediate dimensions are: [1, 128, 9, 480, 720].
+ # - Assume fp16 (2 bytes per value).
+ # Memory required: 1 * 128 * 9 * 480 * 720 * 24 * 2 / 1024**3 = 17.8 GB
+ #
+ # Memory assessment when using tiling:
+ # - Assume everything as above but now HxW is 240x360 by tiling in half
+ # Memory required: 1 * 128 * 9 * 240 * 360 * 24 * 2 / 1024**3 = 4.5 GB
+
+ batch_size, num_channels, num_frames, height, width = z.shape
+
+ overlap_height = int(self.tile_latent_min_height * (1 - self.tile_overlap_factor_height))
+ overlap_width = int(self.tile_latent_min_width * (1 - self.tile_overlap_factor_width))
+ blend_extent_height = int(self.tile_sample_min_height * self.tile_overlap_factor_height)
+ blend_extent_width = int(self.tile_sample_min_width * self.tile_overlap_factor_width)
+ row_limit_height = self.tile_sample_min_height - blend_extent_height
+ row_limit_width = self.tile_sample_min_width - blend_extent_width
+ frame_batch_size = self.num_latent_frames_batch_size
+
+ # Split z into overlapping tiles and decode them separately.
+ # The tiles have an overlap to avoid seams between tiles.
+ rows = []
+ for i in range(0, height, overlap_height):
+ row = []
+ for j in range(0, width, overlap_width):
+ time = []
+ for k in range(num_frames // frame_batch_size):
+ remaining_frames = num_frames % frame_batch_size
+ start_frame = frame_batch_size * k + (0 if k == 0 else remaining_frames)
+ end_frame = frame_batch_size * (k + 1) + remaining_frames
+ tile = z[
+ :,
+ :,
+ start_frame:end_frame,
+ i : i + self.tile_latent_min_height,
+ j : j + self.tile_latent_min_width,
+ ]
+ if self.post_quant_conv is not None:
+ tile = self.post_quant_conv(tile)
+ tile = self.decoder(tile)
+ time.append(tile)
+ self._clear_fake_context_parallel_cache()
+ row.append(torch.cat(time, dim=2))
+ rows.append(row)
+
+ result_rows = []
+ for i, row in enumerate(rows):
+ result_row = []
+ for j, tile in enumerate(row):
+ # blend the above tile and the left tile
+ # to the current tile and add the current tile to the result row
+ if i > 0:
+ tile = self.blend_v(rows[i - 1][j], tile, blend_extent_height)
+ if j > 0:
+ tile = self.blend_h(row[j - 1], tile, blend_extent_width)
+ result_row.append(tile[:, :, :, :row_limit_height, :row_limit_width])
+ result_rows.append(torch.cat(result_row, dim=4))
+
+ dec = torch.cat(result_rows, dim=3)
+
+ if not return_dict:
+ return (dec,)
+
+ return DecoderOutput(sample=dec)
+
+ def forward(
+ self,
+ sample: torch.Tensor,
+ sample_posterior: bool = False,
+ return_dict: bool = True,
+ generator: Optional[torch.Generator] = None,
+ ) -> Union[torch.Tensor, torch.Tensor]:
+ x = sample
+ posterior = self.encode(x).latent_dist
+ if sample_posterior:
+ z = posterior.sample(generator=generator)
+ else:
+ z = posterior.mode()
+ dec = self.decode(z)
+ if not return_dict:
+ return (dec,)
+ return dec
diff --git a/cogvideox/models/transformer3d.py b/cogvideox/models/transformer3d.py
new file mode 100644
index 0000000..5aa7323
--- /dev/null
+++ b/cogvideox/models/transformer3d.py
@@ -0,0 +1,560 @@
+# Copyright 2024 The CogVideoX team, Tsinghua University & ZhipuAI and The HuggingFace Team.
+# All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+from typing import Any, Dict, Optional, Tuple, Union
+
+import os
+import json
+import torch
+import torch.nn.functional as F
+from torch import nn
+
+from diffusers.configuration_utils import ConfigMixin, register_to_config
+from diffusers.utils import is_torch_version, logging
+from diffusers.utils.torch_utils import maybe_allow_in_graph
+from diffusers.models.attention import Attention, FeedForward
+from diffusers.models.attention_processor import AttentionProcessor, CogVideoXAttnProcessor2_0, FusedCogVideoXAttnProcessor2_0
+from diffusers.models.embeddings import CogVideoXPatchEmbed, TimestepEmbedding, Timesteps, get_3d_sincos_pos_embed
+from diffusers.models.modeling_outputs import Transformer2DModelOutput
+from diffusers.models.modeling_utils import ModelMixin
+from diffusers.models.normalization import AdaLayerNorm, CogVideoXLayerNormZero
+
+
+logger = logging.get_logger(__name__) # pylint: disable=invalid-name
+
+
+@maybe_allow_in_graph
+class CogVideoXBlock(nn.Module):
+ r"""
+ Transformer block used in [CogVideoX](https://github.com/THUDM/CogVideo) model.
+
+ Parameters:
+ dim (`int`):
+ The number of channels in the input and output.
+ num_attention_heads (`int`):
+ The number of heads to use for multi-head attention.
+ attention_head_dim (`int`):
+ The number of channels in each head.
+ time_embed_dim (`int`):
+ The number of channels in timestep embedding.
+ dropout (`float`, defaults to `0.0`):
+ The dropout probability to use.
+ activation_fn (`str`, defaults to `"gelu-approximate"`):
+ Activation function to be used in feed-forward.
+ attention_bias (`bool`, defaults to `False`):
+ Whether or not to use bias in attention projection layers.
+ qk_norm (`bool`, defaults to `True`):
+ Whether or not to use normalization after query and key projections in Attention.
+ norm_elementwise_affine (`bool`, defaults to `True`):
+ Whether to use learnable elementwise affine parameters for normalization.
+ norm_eps (`float`, defaults to `1e-5`):
+ Epsilon value for normalization layers.
+ final_dropout (`bool` defaults to `False`):
+ Whether to apply a final dropout after the last feed-forward layer.
+ ff_inner_dim (`int`, *optional*, defaults to `None`):
+ Custom hidden dimension of Feed-forward layer. If not provided, `4 * dim` is used.
+ ff_bias (`bool`, defaults to `True`):
+ Whether or not to use bias in Feed-forward layer.
+ attention_out_bias (`bool`, defaults to `True`):
+ Whether or not to use bias in Attention output projection layer.
+ """
+
+ def __init__(
+ self,
+ dim: int,
+ num_attention_heads: int,
+ attention_head_dim: int,
+ time_embed_dim: int,
+ dropout: float = 0.0,
+ activation_fn: str = "gelu-approximate",
+ attention_bias: bool = False,
+ qk_norm: bool = True,
+ norm_elementwise_affine: bool = True,
+ norm_eps: float = 1e-5,
+ final_dropout: bool = True,
+ ff_inner_dim: Optional[int] = None,
+ ff_bias: bool = True,
+ attention_out_bias: bool = True,
+ ):
+ super().__init__()
+
+ # 1. Self Attention
+ self.norm1 = CogVideoXLayerNormZero(time_embed_dim, dim, norm_elementwise_affine, norm_eps, bias=True)
+
+ self.attn1 = Attention(
+ query_dim=dim,
+ dim_head=attention_head_dim,
+ heads=num_attention_heads,
+ qk_norm="layer_norm" if qk_norm else None,
+ eps=1e-6,
+ bias=attention_bias,
+ out_bias=attention_out_bias,
+ processor=CogVideoXAttnProcessor2_0(),
+ )
+
+ # 2. Feed Forward
+ self.norm2 = CogVideoXLayerNormZero(time_embed_dim, dim, norm_elementwise_affine, norm_eps, bias=True)
+
+ self.ff = FeedForward(
+ dim,
+ dropout=dropout,
+ activation_fn=activation_fn,
+ final_dropout=final_dropout,
+ inner_dim=ff_inner_dim,
+ bias=ff_bias,
+ )
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ encoder_hidden_states: torch.Tensor,
+ temb: torch.Tensor,
+ image_rotary_emb: Optional[Tuple[torch.Tensor, torch.Tensor]] = None,
+ ) -> torch.Tensor:
+ text_seq_length = encoder_hidden_states.size(1)
+
+ # norm & modulate
+ norm_hidden_states, norm_encoder_hidden_states, gate_msa, enc_gate_msa = self.norm1(
+ hidden_states, encoder_hidden_states, temb
+ )
+
+ # attention
+ attn_hidden_states, attn_encoder_hidden_states = self.attn1(
+ hidden_states=norm_hidden_states,
+ encoder_hidden_states=norm_encoder_hidden_states,
+ image_rotary_emb=image_rotary_emb,
+ )
+
+ hidden_states = hidden_states + gate_msa * attn_hidden_states
+ encoder_hidden_states = encoder_hidden_states + enc_gate_msa * attn_encoder_hidden_states
+
+ # norm & modulate
+ norm_hidden_states, norm_encoder_hidden_states, gate_ff, enc_gate_ff = self.norm2(
+ hidden_states, encoder_hidden_states, temb
+ )
+
+ # feed-forward
+ norm_hidden_states = torch.cat([norm_encoder_hidden_states, norm_hidden_states], dim=1)
+ ff_output = self.ff(norm_hidden_states)
+
+ hidden_states = hidden_states + gate_ff * ff_output[:, text_seq_length:]
+ encoder_hidden_states = encoder_hidden_states + enc_gate_ff * ff_output[:, :text_seq_length]
+
+ return hidden_states, encoder_hidden_states
+
+
+class CogVideoXTransformer3DModel(ModelMixin, ConfigMixin):
+ """
+ A Transformer model for video-like data in [CogVideoX](https://github.com/THUDM/CogVideo).
+
+ Parameters:
+ num_attention_heads (`int`, defaults to `30`):
+ The number of heads to use for multi-head attention.
+ attention_head_dim (`int`, defaults to `64`):
+ The number of channels in each head.
+ in_channels (`int`, defaults to `16`):
+ The number of channels in the input.
+ out_channels (`int`, *optional*, defaults to `16`):
+ The number of channels in the output.
+ flip_sin_to_cos (`bool`, defaults to `True`):
+ Whether to flip the sin to cos in the time embedding.
+ time_embed_dim (`int`, defaults to `512`):
+ Output dimension of timestep embeddings.
+ text_embed_dim (`int`, defaults to `4096`):
+ Input dimension of text embeddings from the text encoder.
+ num_layers (`int`, defaults to `30`):
+ The number of layers of Transformer blocks to use.
+ dropout (`float`, defaults to `0.0`):
+ The dropout probability to use.
+ attention_bias (`bool`, defaults to `True`):
+ Whether or not to use bias in the attention projection layers.
+ sample_width (`int`, defaults to `90`):
+ The width of the input latents.
+ sample_height (`int`, defaults to `60`):
+ The height of the input latents.
+ sample_frames (`int`, defaults to `49`):
+ The number of frames in the input latents. Note that this parameter was incorrectly initialized to 49
+ instead of 13 because CogVideoX processed 13 latent frames at once in its default and recommended settings,
+ but cannot be changed to the correct value to ensure backwards compatibility. To create a transformer with
+ K latent frames, the correct value to pass here would be: ((K - 1) * temporal_compression_ratio + 1).
+ patch_size (`int`, defaults to `2`):
+ The size of the patches to use in the patch embedding layer.
+ temporal_compression_ratio (`int`, defaults to `4`):
+ The compression ratio across the temporal dimension. See documentation for `sample_frames`.
+ max_text_seq_length (`int`, defaults to `226`):
+ The maximum sequence length of the input text embeddings.
+ activation_fn (`str`, defaults to `"gelu-approximate"`):
+ Activation function to use in feed-forward.
+ timestep_activation_fn (`str`, defaults to `"silu"`):
+ Activation function to use when generating the timestep embeddings.
+ norm_elementwise_affine (`bool`, defaults to `True`):
+ Whether or not to use elementwise affine in normalization layers.
+ norm_eps (`float`, defaults to `1e-5`):
+ The epsilon value to use in normalization layers.
+ spatial_interpolation_scale (`float`, defaults to `1.875`):
+ Scaling factor to apply in 3D positional embeddings across spatial dimensions.
+ temporal_interpolation_scale (`float`, defaults to `1.0`):
+ Scaling factor to apply in 3D positional embeddings across temporal dimensions.
+ """
+
+ _supports_gradient_checkpointing = True
+
+ @register_to_config
+ def __init__(
+ self,
+ num_attention_heads: int = 30,
+ attention_head_dim: int = 64,
+ in_channels: int = 16,
+ out_channels: Optional[int] = 16,
+ flip_sin_to_cos: bool = True,
+ freq_shift: int = 0,
+ time_embed_dim: int = 512,
+ text_embed_dim: int = 4096,
+ num_layers: int = 30,
+ dropout: float = 0.0,
+ attention_bias: bool = True,
+ sample_width: int = 90,
+ sample_height: int = 60,
+ sample_frames: int = 49,
+ patch_size: int = 2,
+ temporal_compression_ratio: int = 4,
+ max_text_seq_length: int = 226,
+ activation_fn: str = "gelu-approximate",
+ timestep_activation_fn: str = "silu",
+ norm_elementwise_affine: bool = True,
+ norm_eps: float = 1e-5,
+ spatial_interpolation_scale: float = 1.875,
+ temporal_interpolation_scale: float = 1.0,
+ use_rotary_positional_embeddings: bool = False,
+ ):
+ super().__init__()
+ inner_dim = num_attention_heads * attention_head_dim
+
+ post_patch_height = sample_height // patch_size
+ post_patch_width = sample_width // patch_size
+ post_time_compression_frames = (sample_frames - 1) // temporal_compression_ratio + 1
+ self.num_patches = post_patch_height * post_patch_width * post_time_compression_frames
+ self.post_patch_height = post_patch_height
+ self.post_patch_width = post_patch_width
+ self.post_time_compression_frames = post_time_compression_frames
+ self.patch_size = patch_size
+
+ # 1. Patch embedding
+ self.patch_embed = CogVideoXPatchEmbed(patch_size, in_channels, inner_dim, text_embed_dim, bias=True)
+ self.embedding_dropout = nn.Dropout(dropout)
+
+ # 2. 3D positional embeddings
+ spatial_pos_embedding = get_3d_sincos_pos_embed(
+ inner_dim,
+ (post_patch_width, post_patch_height),
+ post_time_compression_frames,
+ spatial_interpolation_scale,
+ temporal_interpolation_scale,
+ )
+ spatial_pos_embedding = torch.from_numpy(spatial_pos_embedding).flatten(0, 1)
+ pos_embedding = torch.zeros(1, max_text_seq_length + self.num_patches, inner_dim, requires_grad=False)
+ pos_embedding.data[:, max_text_seq_length:].copy_(spatial_pos_embedding)
+ self.register_buffer("pos_embedding", pos_embedding, persistent=False)
+
+ # 3. Time embeddings
+ self.time_proj = Timesteps(inner_dim, flip_sin_to_cos, freq_shift)
+ self.time_embedding = TimestepEmbedding(inner_dim, time_embed_dim, timestep_activation_fn)
+
+ # 4. Define spatio-temporal transformers blocks
+ self.transformer_blocks = nn.ModuleList(
+ [
+ CogVideoXBlock(
+ dim=inner_dim,
+ num_attention_heads=num_attention_heads,
+ attention_head_dim=attention_head_dim,
+ time_embed_dim=time_embed_dim,
+ dropout=dropout,
+ activation_fn=activation_fn,
+ attention_bias=attention_bias,
+ norm_elementwise_affine=norm_elementwise_affine,
+ norm_eps=norm_eps,
+ )
+ for _ in range(num_layers)
+ ]
+ )
+ self.norm_final = nn.LayerNorm(inner_dim, norm_eps, norm_elementwise_affine)
+
+ # 5. Output blocks
+ self.norm_out = AdaLayerNorm(
+ embedding_dim=time_embed_dim,
+ output_dim=2 * inner_dim,
+ norm_elementwise_affine=norm_elementwise_affine,
+ norm_eps=norm_eps,
+ chunk_dim=1,
+ )
+ self.proj_out = nn.Linear(inner_dim, patch_size * patch_size * out_channels)
+
+ self.gradient_checkpointing = False
+
+ def _set_gradient_checkpointing(self, module, value=False):
+ self.gradient_checkpointing = value
+
+ @property
+ # Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.attn_processors
+ def attn_processors(self) -> Dict[str, AttentionProcessor]:
+ r"""
+ Returns:
+ `dict` of attention processors: A dictionary containing all attention processors used in the model with
+ indexed by its weight name.
+ """
+ # set recursively
+ processors = {}
+
+ def fn_recursive_add_processors(name: str, module: torch.nn.Module, processors: Dict[str, AttentionProcessor]):
+ if hasattr(module, "get_processor"):
+ processors[f"{name}.processor"] = module.get_processor()
+
+ for sub_name, child in module.named_children():
+ fn_recursive_add_processors(f"{name}.{sub_name}", child, processors)
+
+ return processors
+
+ for name, module in self.named_children():
+ fn_recursive_add_processors(name, module, processors)
+
+ return processors
+
+ # Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.set_attn_processor
+ def set_attn_processor(self, processor: Union[AttentionProcessor, Dict[str, AttentionProcessor]]):
+ r"""
+ Sets the attention processor to use to compute attention.
+
+ Parameters:
+ processor (`dict` of `AttentionProcessor` or only `AttentionProcessor`):
+ The instantiated processor class or a dictionary of processor classes that will be set as the processor
+ for **all** `Attention` layers.
+
+ If `processor` is a dict, the key needs to define the path to the corresponding cross attention
+ processor. This is strongly recommended when setting trainable attention processors.
+
+ """
+ count = len(self.attn_processors.keys())
+
+ if isinstance(processor, dict) and len(processor) != count:
+ raise ValueError(
+ f"A dict of processors was passed, but the number of processors {len(processor)} does not match the"
+ f" number of attention layers: {count}. Please make sure to pass {count} processor classes."
+ )
+
+ def fn_recursive_attn_processor(name: str, module: torch.nn.Module, processor):
+ if hasattr(module, "set_processor"):
+ if not isinstance(processor, dict):
+ module.set_processor(processor)
+ else:
+ module.set_processor(processor.pop(f"{name}.processor"))
+
+ for sub_name, child in module.named_children():
+ fn_recursive_attn_processor(f"{name}.{sub_name}", child, processor)
+
+ for name, module in self.named_children():
+ fn_recursive_attn_processor(name, module, processor)
+
+ # Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.fuse_qkv_projections with FusedAttnProcessor2_0->FusedCogVideoXAttnProcessor2_0
+ def fuse_qkv_projections(self):
+ """
+ Enables fused QKV projections. For self-attention modules, all projection matrices (i.e., query, key, value)
+ are fused. For cross-attention modules, key and value projection matrices are fused.
+
+
+
+ This API is 🧪 experimental.
+
+
+ """
+ self.original_attn_processors = None
+
+ for _, attn_processor in self.attn_processors.items():
+ if "Added" in str(attn_processor.__class__.__name__):
+ raise ValueError("`fuse_qkv_projections()` is not supported for models having added KV projections.")
+
+ self.original_attn_processors = self.attn_processors
+
+ for module in self.modules():
+ if isinstance(module, Attention):
+ module.fuse_projections(fuse=True)
+
+ self.set_attn_processor(FusedCogVideoXAttnProcessor2_0())
+
+ # Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.unfuse_qkv_projections
+ def unfuse_qkv_projections(self):
+ """Disables the fused QKV projection if enabled.
+
+
+
+ This API is 🧪 experimental.
+
+
+
+ """
+ if self.original_attn_processors is not None:
+ self.set_attn_processor(self.original_attn_processors)
+
+ def forward(
+ self,
+ hidden_states: torch.Tensor,
+ encoder_hidden_states: torch.Tensor,
+ timestep: Union[int, float, torch.LongTensor],
+ timestep_cond: Optional[torch.Tensor] = None,
+ inpaint_latents: Optional[torch.Tensor] = None,
+ image_rotary_emb: Optional[Tuple[torch.Tensor, torch.Tensor]] = None,
+ return_dict: bool = True,
+ ):
+ batch_size, num_frames, channels, height, width = hidden_states.shape
+
+ # 1. Time embedding
+ timesteps = timestep
+ t_emb = self.time_proj(timesteps)
+
+ # timesteps does not contain any weights and will always return f32 tensors
+ # but time_embedding might actually be running in fp16. so we need to cast here.
+ # there might be better ways to encapsulate this.
+ t_emb = t_emb.to(dtype=hidden_states.dtype)
+ emb = self.time_embedding(t_emb, timestep_cond)
+
+ # 2. Patch embedding
+ if inpaint_latents is not None:
+ hidden_states = torch.concat([hidden_states, inpaint_latents], 2)
+ hidden_states = self.patch_embed(encoder_hidden_states, hidden_states)
+
+ # 3. Position embedding
+ text_seq_length = encoder_hidden_states.shape[1]
+ if not self.config.use_rotary_positional_embeddings:
+ seq_length = height * width * num_frames // (self.config.patch_size**2)
+ # pos_embeds = self.pos_embedding[:, : text_seq_length + seq_length]
+ pos_embeds = self.pos_embedding
+ emb_size = hidden_states.size()[-1]
+ pos_embeds_without_text = pos_embeds[:, text_seq_length: ].view(1, self.post_time_compression_frames, self.post_patch_height, self.post_patch_width, emb_size)
+ pos_embeds_without_text = pos_embeds_without_text.permute([0, 4, 1, 2, 3])
+ pos_embeds_without_text = F.interpolate(pos_embeds_without_text,size=[self.post_time_compression_frames, height // self.config.patch_size, width // self.config.patch_size],mode='trilinear',align_corners=False)
+ pos_embeds_without_text = pos_embeds_without_text.permute([0, 2, 3, 4, 1]).view(1, -1, emb_size)
+ pos_embeds = torch.cat([pos_embeds[:, :text_seq_length], pos_embeds_without_text], dim = 1)
+ pos_embeds = pos_embeds[:, : text_seq_length + seq_length]
+ hidden_states = hidden_states + pos_embeds
+ hidden_states = self.embedding_dropout(hidden_states)
+
+ encoder_hidden_states = hidden_states[:, :text_seq_length]
+ hidden_states = hidden_states[:, text_seq_length:]
+
+ # 4. Transformer blocks
+ for i, block in enumerate(self.transformer_blocks):
+ if self.training and self.gradient_checkpointing:
+
+ def create_custom_forward(module):
+ def custom_forward(*inputs):
+ return module(*inputs)
+
+ return custom_forward
+
+ ckpt_kwargs: Dict[str, Any] = {"use_reentrant": False} if is_torch_version(">=", "1.11.0") else {}
+ hidden_states, encoder_hidden_states = torch.utils.checkpoint.checkpoint(
+ create_custom_forward(block),
+ hidden_states,
+ encoder_hidden_states,
+ emb,
+ image_rotary_emb,
+ **ckpt_kwargs,
+ )
+ else:
+ hidden_states, encoder_hidden_states = block(
+ hidden_states=hidden_states,
+ encoder_hidden_states=encoder_hidden_states,
+ temb=emb,
+ image_rotary_emb=image_rotary_emb,
+ )
+
+ if not self.config.use_rotary_positional_embeddings:
+ # CogVideoX-2B
+ hidden_states = self.norm_final(hidden_states)
+ else:
+ # CogVideoX-5B
+ hidden_states = torch.cat([encoder_hidden_states, hidden_states], dim=1)
+ hidden_states = self.norm_final(hidden_states)
+ hidden_states = hidden_states[:, text_seq_length:]
+
+ # 5. Final block
+ hidden_states = self.norm_out(hidden_states, temb=emb)
+ hidden_states = self.proj_out(hidden_states)
+
+ # 6. Unpatchify
+ p = self.config.patch_size
+ output = hidden_states.reshape(batch_size, num_frames, height // p, width // p, channels, p, p)
+ output = output.permute(0, 1, 4, 2, 5, 3, 6).flatten(5, 6).flatten(3, 4)
+
+ if not return_dict:
+ return (output,)
+ return Transformer2DModelOutput(sample=output)
+
+ @classmethod
+ def from_pretrained_2d(cls, pretrained_model_path, subfolder=None, transformer_additional_kwargs={}):
+ if subfolder is not None:
+ pretrained_model_path = os.path.join(pretrained_model_path, subfolder)
+ print(f"loaded 3D transformer's pretrained weights from {pretrained_model_path} ...")
+
+ config_file = os.path.join(pretrained_model_path, 'config.json')
+ if not os.path.isfile(config_file):
+ raise RuntimeError(f"{config_file} does not exist")
+ with open(config_file, "r") as f:
+ config = json.load(f)
+
+ from diffusers.utils import WEIGHTS_NAME
+ model = cls.from_config(config, **transformer_additional_kwargs)
+ model_file = os.path.join(pretrained_model_path, WEIGHTS_NAME)
+ model_file_safetensors = model_file.replace(".bin", ".safetensors")
+ if os.path.exists(model_file_safetensors):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(model_file_safetensors)
+ else:
+ if not os.path.isfile(model_file):
+ raise RuntimeError(f"{model_file} does not exist")
+ state_dict = torch.load(model_file, map_location="cpu")
+
+ if model.state_dict()['patch_embed.proj.weight'].size() != state_dict['patch_embed.proj.weight'].size():
+ new_shape = model.state_dict()['patch_embed.proj.weight'].size()
+ if len(new_shape) == 5:
+ state_dict['patch_embed.proj.weight'] = state_dict['patch_embed.proj.weight'].unsqueeze(2).expand(new_shape).clone()
+ state_dict['patch_embed.proj.weight'][:, :, :-1] = 0
+ else:
+ if model.state_dict()['patch_embed.proj.weight'].size()[1] > state_dict['patch_embed.proj.weight'].size()[1]:
+ model.state_dict()['patch_embed.proj.weight'][:, :state_dict['patch_embed.proj.weight'].size()[1], :, :] = state_dict['patch_embed.proj.weight']
+ model.state_dict()['patch_embed.proj.weight'][:, state_dict['patch_embed.proj.weight'].size()[1]:, :, :] = 0
+ state_dict['patch_embed.proj.weight'] = model.state_dict()['patch_embed.proj.weight']
+ else:
+ model.state_dict()['patch_embed.proj.weight'][:, :, :, :] = state_dict['patch_embed.proj.weight'][:, :model.state_dict()['patch_embed.proj.weight'].size()[1], :, :]
+ state_dict['patch_embed.proj.weight'] = model.state_dict()['patch_embed.proj.weight']
+
+ tmp_state_dict = {}
+ for key in state_dict:
+ if key in model.state_dict().keys() and model.state_dict()[key].size() == state_dict[key].size():
+ tmp_state_dict[key] = state_dict[key]
+ else:
+ print(key, "Size don't match, skip")
+ state_dict = tmp_state_dict
+
+ m, u = model.load_state_dict(state_dict, strict=False)
+ print(f"### missing keys: {len(m)}; \n### unexpected keys: {len(u)};")
+ print(m)
+
+ params = [p.numel() if "mamba" in n else 0 for n, p in model.named_parameters()]
+ print(f"### Mamba Parameters: {sum(params) / 1e6} M")
+
+ params = [p.numel() if "attn1." in n else 0 for n, p in model.named_parameters()]
+ print(f"### attn1 Parameters: {sum(params) / 1e6} M")
+
+ return model
\ No newline at end of file
diff --git a/cogvideox/pipeline/pipeline_cogvideox.py b/cogvideox/pipeline/pipeline_cogvideox.py
new file mode 100644
index 0000000..6edefa2
--- /dev/null
+++ b/cogvideox/pipeline/pipeline_cogvideox.py
@@ -0,0 +1,751 @@
+# Copyright 2024 The CogVideoX team, Tsinghua University & ZhipuAI and The HuggingFace Team.
+# All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import inspect
+import math
+from dataclasses import dataclass
+from typing import Callable, Dict, List, Optional, Tuple, Union
+
+import torch
+from transformers import T5EncoderModel, T5Tokenizer
+
+from diffusers.callbacks import MultiPipelineCallbacks, PipelineCallback
+from diffusers.models import AutoencoderKLCogVideoX, CogVideoXTransformer3DModel
+from diffusers.models.embeddings import get_3d_rotary_pos_embed
+from diffusers.pipelines.pipeline_utils import DiffusionPipeline
+from diffusers.schedulers import CogVideoXDDIMScheduler, CogVideoXDPMScheduler
+from diffusers.utils import BaseOutput, logging, replace_example_docstring
+from diffusers.utils.torch_utils import randn_tensor
+from diffusers.video_processor import VideoProcessor
+
+
+logger = logging.get_logger(__name__) # pylint: disable=invalid-name
+
+
+EXAMPLE_DOC_STRING = """
+ Examples:
+ ```python
+ >>> import torch
+ >>> from diffusers import CogVideoX_FUN_Pipeline
+ >>> from diffusers.utils import export_to_video
+
+ >>> # Models: "THUDM/CogVideoX-2b" or "THUDM/CogVideoX-5b"
+ >>> pipe = CogVideoX_FUN_Pipeline.from_pretrained("THUDM/CogVideoX-2b", torch_dtype=torch.float16).to("cuda")
+ >>> prompt = (
+ ... "A panda, dressed in a small, red jacket and a tiny hat, sits on a wooden stool in a serene bamboo forest. "
+ ... "The panda's fluffy paws strum a miniature acoustic guitar, producing soft, melodic tunes. Nearby, a few other "
+ ... "pandas gather, watching curiously and some clapping in rhythm. Sunlight filters through the tall bamboo, "
+ ... "casting a gentle glow on the scene. The panda's face is expressive, showing concentration and joy as it plays. "
+ ... "The background includes a small, flowing stream and vibrant green foliage, enhancing the peaceful and magical "
+ ... "atmosphere of this unique musical performance."
+ ... )
+ >>> video = pipe(prompt=prompt, guidance_scale=6, num_inference_steps=50).frames[0]
+ >>> export_to_video(video, "output.mp4", fps=8)
+ ```
+"""
+
+
+# Similar to diffusers.pipelines.hunyuandit.pipeline_hunyuandit.get_resize_crop_region_for_grid
+def get_resize_crop_region_for_grid(src, tgt_width, tgt_height):
+ tw = tgt_width
+ th = tgt_height
+ h, w = src
+ r = h / w
+ if r > (th / tw):
+ resize_height = th
+ resize_width = int(round(th / h * w))
+ else:
+ resize_width = tw
+ resize_height = int(round(tw / w * h))
+
+ crop_top = int(round((th - resize_height) / 2.0))
+ crop_left = int(round((tw - resize_width) / 2.0))
+
+ return (crop_top, crop_left), (crop_top + resize_height, crop_left + resize_width)
+
+
+# Copied from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion.retrieve_timesteps
+def retrieve_timesteps(
+ scheduler,
+ num_inference_steps: Optional[int] = None,
+ device: Optional[Union[str, torch.device]] = None,
+ timesteps: Optional[List[int]] = None,
+ sigmas: Optional[List[float]] = None,
+ **kwargs,
+):
+ """
+ Calls the scheduler's `set_timesteps` method and retrieves timesteps from the scheduler after the call. Handles
+ custom timesteps. Any kwargs will be supplied to `scheduler.set_timesteps`.
+
+ Args:
+ scheduler (`SchedulerMixin`):
+ The scheduler to get timesteps from.
+ num_inference_steps (`int`):
+ The number of diffusion steps used when generating samples with a pre-trained model. If used, `timesteps`
+ must be `None`.
+ device (`str` or `torch.device`, *optional*):
+ The device to which the timesteps should be moved to. If `None`, the timesteps are not moved.
+ timesteps (`List[int]`, *optional*):
+ Custom timesteps used to override the timestep spacing strategy of the scheduler. If `timesteps` is passed,
+ `num_inference_steps` and `sigmas` must be `None`.
+ sigmas (`List[float]`, *optional*):
+ Custom sigmas used to override the timestep spacing strategy of the scheduler. If `sigmas` is passed,
+ `num_inference_steps` and `timesteps` must be `None`.
+
+ Returns:
+ `Tuple[torch.Tensor, int]`: A tuple where the first element is the timestep schedule from the scheduler and the
+ second element is the number of inference steps.
+ """
+ if timesteps is not None and sigmas is not None:
+ raise ValueError("Only one of `timesteps` or `sigmas` can be passed. Please choose one to set custom values")
+ if timesteps is not None:
+ accepts_timesteps = "timesteps" in set(inspect.signature(scheduler.set_timesteps).parameters.keys())
+ if not accepts_timesteps:
+ raise ValueError(
+ f"The current scheduler class {scheduler.__class__}'s `set_timesteps` does not support custom"
+ f" timestep schedules. Please check whether you are using the correct scheduler."
+ )
+ scheduler.set_timesteps(timesteps=timesteps, device=device, **kwargs)
+ timesteps = scheduler.timesteps
+ num_inference_steps = len(timesteps)
+ elif sigmas is not None:
+ accept_sigmas = "sigmas" in set(inspect.signature(scheduler.set_timesteps).parameters.keys())
+ if not accept_sigmas:
+ raise ValueError(
+ f"The current scheduler class {scheduler.__class__}'s `set_timesteps` does not support custom"
+ f" sigmas schedules. Please check whether you are using the correct scheduler."
+ )
+ scheduler.set_timesteps(sigmas=sigmas, device=device, **kwargs)
+ timesteps = scheduler.timesteps
+ num_inference_steps = len(timesteps)
+ else:
+ scheduler.set_timesteps(num_inference_steps, device=device, **kwargs)
+ timesteps = scheduler.timesteps
+ return timesteps, num_inference_steps
+
+
+@dataclass
+class CogVideoX_FUN_PipelineOutput(BaseOutput):
+ r"""
+ Output class for CogVideo pipelines.
+
+ Args:
+ video (`torch.Tensor`, `np.ndarray`, or List[List[PIL.Image.Image]]):
+ List of video outputs - It can be a nested list of length `batch_size,` with each sub-list containing
+ denoised PIL image sequences of length `num_frames.` It can also be a NumPy array or Torch tensor of shape
+ `(batch_size, num_frames, channels, height, width)`.
+ """
+
+ videos: torch.Tensor
+
+
+class CogVideoX_FUN_Pipeline(DiffusionPipeline):
+ r"""
+ Pipeline for text-to-video generation using CogVideoX_FUN.
+
+ This model inherits from [`DiffusionPipeline`]. Check the superclass documentation for the generic methods the
+ library implements for all the pipelines (such as downloading or saving, running on a particular device, etc.)
+
+ Args:
+ vae ([`AutoencoderKL`]):
+ Variational Auto-Encoder (VAE) Model to encode and decode videos to and from latent representations.
+ text_encoder ([`T5EncoderModel`]):
+ Frozen text-encoder. CogVideoX uses
+ [T5](https://huggingface.co/docs/transformers/model_doc/t5#transformers.T5EncoderModel); specifically the
+ [t5-v1_1-xxl](https://huggingface.co/PixArt-alpha/PixArt-alpha/tree/main/t5-v1_1-xxl) variant.
+ tokenizer (`T5Tokenizer`):
+ Tokenizer of class
+ [T5Tokenizer](https://huggingface.co/docs/transformers/model_doc/t5#transformers.T5Tokenizer).
+ transformer ([`CogVideoXTransformer3DModel`]):
+ A text conditioned `CogVideoXTransformer3DModel` to denoise the encoded video latents.
+ scheduler ([`SchedulerMixin`]):
+ A scheduler to be used in combination with `transformer` to denoise the encoded video latents.
+ """
+
+ _optional_components = []
+ model_cpu_offload_seq = "text_encoder->transformer->vae"
+
+ _callback_tensor_inputs = [
+ "latents",
+ "prompt_embeds",
+ "negative_prompt_embeds",
+ ]
+
+ def __init__(
+ self,
+ tokenizer: T5Tokenizer,
+ text_encoder: T5EncoderModel,
+ vae: AutoencoderKLCogVideoX,
+ transformer: CogVideoXTransformer3DModel,
+ scheduler: Union[CogVideoXDDIMScheduler, CogVideoXDPMScheduler],
+ ):
+ super().__init__()
+
+ self.register_modules(
+ tokenizer=tokenizer, text_encoder=text_encoder, vae=vae, transformer=transformer, scheduler=scheduler
+ )
+ self.vae_scale_factor_spatial = (
+ 2 ** (len(self.vae.config.block_out_channels) - 1) if hasattr(self, "vae") and self.vae is not None else 8
+ )
+ self.vae_scale_factor_temporal = (
+ self.vae.config.temporal_compression_ratio if hasattr(self, "vae") and self.vae is not None else 4
+ )
+
+ self.video_processor = VideoProcessor(vae_scale_factor=self.vae_scale_factor_spatial)
+
+ def _get_t5_prompt_embeds(
+ self,
+ prompt: Union[str, List[str]] = None,
+ num_videos_per_prompt: int = 1,
+ max_sequence_length: int = 226,
+ device: Optional[torch.device] = None,
+ dtype: Optional[torch.dtype] = None,
+ ):
+ device = device or self._execution_device
+ dtype = dtype or self.text_encoder.dtype
+
+ prompt = [prompt] if isinstance(prompt, str) else prompt
+ batch_size = len(prompt)
+
+ text_inputs = self.tokenizer(
+ prompt,
+ padding="max_length",
+ max_length=max_sequence_length,
+ truncation=True,
+ add_special_tokens=True,
+ return_tensors="pt",
+ )
+ text_input_ids = text_inputs.input_ids
+ untruncated_ids = self.tokenizer(prompt, padding="longest", return_tensors="pt").input_ids
+
+ if untruncated_ids.shape[-1] >= text_input_ids.shape[-1] and not torch.equal(text_input_ids, untruncated_ids):
+ removed_text = self.tokenizer.batch_decode(untruncated_ids[:, max_sequence_length - 1 : -1])
+ logger.warning(
+ "The following part of your input was truncated because `max_sequence_length` is set to "
+ f" {max_sequence_length} tokens: {removed_text}"
+ )
+
+ prompt_embeds = self.text_encoder(text_input_ids.to(device))[0]
+ prompt_embeds = prompt_embeds.to(dtype=dtype, device=device)
+
+ # duplicate text embeddings for each generation per prompt, using mps friendly method
+ _, seq_len, _ = prompt_embeds.shape
+ prompt_embeds = prompt_embeds.repeat(1, num_videos_per_prompt, 1)
+ prompt_embeds = prompt_embeds.view(batch_size * num_videos_per_prompt, seq_len, -1)
+
+ return prompt_embeds
+
+ def encode_prompt(
+ self,
+ prompt: Union[str, List[str]],
+ negative_prompt: Optional[Union[str, List[str]]] = None,
+ do_classifier_free_guidance: bool = True,
+ num_videos_per_prompt: int = 1,
+ prompt_embeds: Optional[torch.Tensor] = None,
+ negative_prompt_embeds: Optional[torch.Tensor] = None,
+ max_sequence_length: int = 226,
+ device: Optional[torch.device] = None,
+ dtype: Optional[torch.dtype] = None,
+ ):
+ r"""
+ Encodes the prompt into text encoder hidden states.
+
+ Args:
+ prompt (`str` or `List[str]`, *optional*):
+ prompt to be encoded
+ negative_prompt (`str` or `List[str]`, *optional*):
+ The prompt or prompts not to guide the image generation. If not defined, one has to pass
+ `negative_prompt_embeds` instead. Ignored when not using guidance (i.e., ignored if `guidance_scale` is
+ less than `1`).
+ do_classifier_free_guidance (`bool`, *optional*, defaults to `True`):
+ Whether to use classifier free guidance or not.
+ num_videos_per_prompt (`int`, *optional*, defaults to 1):
+ Number of videos that should be generated per prompt. torch device to place the resulting embeddings on
+ prompt_embeds (`torch.Tensor`, *optional*):
+ Pre-generated text embeddings. Can be used to easily tweak text inputs, *e.g.* prompt weighting. If not
+ provided, text embeddings will be generated from `prompt` input argument.
+ negative_prompt_embeds (`torch.Tensor`, *optional*):
+ Pre-generated negative text embeddings. Can be used to easily tweak text inputs, *e.g.* prompt
+ weighting. If not provided, negative_prompt_embeds will be generated from `negative_prompt` input
+ argument.
+ device: (`torch.device`, *optional*):
+ torch device
+ dtype: (`torch.dtype`, *optional*):
+ torch dtype
+ """
+ device = device or self._execution_device
+
+ prompt = [prompt] if isinstance(prompt, str) else prompt
+ if prompt is not None:
+ batch_size = len(prompt)
+ else:
+ batch_size = prompt_embeds.shape[0]
+
+ if prompt_embeds is None:
+ prompt_embeds = self._get_t5_prompt_embeds(
+ prompt=prompt,
+ num_videos_per_prompt=num_videos_per_prompt,
+ max_sequence_length=max_sequence_length,
+ device=device,
+ dtype=dtype,
+ )
+
+ if do_classifier_free_guidance and negative_prompt_embeds is None:
+ negative_prompt = negative_prompt or ""
+ negative_prompt = batch_size * [negative_prompt] if isinstance(negative_prompt, str) else negative_prompt
+
+ if prompt is not None and type(prompt) is not type(negative_prompt):
+ raise TypeError(
+ f"`negative_prompt` should be the same type to `prompt`, but got {type(negative_prompt)} !="
+ f" {type(prompt)}."
+ )
+ elif batch_size != len(negative_prompt):
+ raise ValueError(
+ f"`negative_prompt`: {negative_prompt} has batch size {len(negative_prompt)}, but `prompt`:"
+ f" {prompt} has batch size {batch_size}. Please make sure that passed `negative_prompt` matches"
+ " the batch size of `prompt`."
+ )
+
+ negative_prompt_embeds = self._get_t5_prompt_embeds(
+ prompt=negative_prompt,
+ num_videos_per_prompt=num_videos_per_prompt,
+ max_sequence_length=max_sequence_length,
+ device=device,
+ dtype=dtype,
+ )
+
+ return prompt_embeds, negative_prompt_embeds
+
+ def prepare_latents(
+ self, batch_size, num_channels_latents, num_frames, height, width, dtype, device, generator, latents=None
+ ):
+ shape = (
+ batch_size,
+ (num_frames - 1) // self.vae_scale_factor_temporal + 1,
+ num_channels_latents,
+ height // self.vae_scale_factor_spatial,
+ width // self.vae_scale_factor_spatial,
+ )
+ if isinstance(generator, list) and len(generator) != batch_size:
+ raise ValueError(
+ f"You have passed a list of generators of length {len(generator)}, but requested an effective batch"
+ f" size of {batch_size}. Make sure the batch size matches the length of the generators."
+ )
+
+ if latents is None:
+ latents = randn_tensor(shape, generator=generator, device=device, dtype=dtype)
+ else:
+ latents = latents.to(device)
+
+ # scale the initial noise by the standard deviation required by the scheduler
+ latents = latents * self.scheduler.init_noise_sigma
+ return latents
+
+ def decode_latents(self, latents: torch.Tensor) -> torch.Tensor:
+ latents = latents.permute(0, 2, 1, 3, 4) # [batch_size, num_channels, num_frames, height, width]
+ latents = 1 / self.vae.config.scaling_factor * latents
+
+ frames = self.vae.decode(latents).sample
+ frames = (frames / 2 + 0.5).clamp(0, 1)
+ # we always cast to float32 as this does not cause significant overhead and is compatible with bfloa16
+ frames = frames.cpu().float().numpy()
+ return frames
+
+ # Copied from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion.StableDiffusionPipeline.prepare_extra_step_kwargs
+ def prepare_extra_step_kwargs(self, generator, eta):
+ # prepare extra kwargs for the scheduler step, since not all schedulers have the same signature
+ # eta (η) is only used with the DDIMScheduler, it will be ignored for other schedulers.
+ # eta corresponds to η in DDIM paper: https://arxiv.org/abs/2010.02502
+ # and should be between [0, 1]
+
+ accepts_eta = "eta" in set(inspect.signature(self.scheduler.step).parameters.keys())
+ extra_step_kwargs = {}
+ if accepts_eta:
+ extra_step_kwargs["eta"] = eta
+
+ # check if the scheduler accepts generator
+ accepts_generator = "generator" in set(inspect.signature(self.scheduler.step).parameters.keys())
+ if accepts_generator:
+ extra_step_kwargs["generator"] = generator
+ return extra_step_kwargs
+
+ # Copied from diffusers.pipelines.latte.pipeline_latte.LattePipeline.check_inputs
+ def check_inputs(
+ self,
+ prompt,
+ height,
+ width,
+ negative_prompt,
+ callback_on_step_end_tensor_inputs,
+ prompt_embeds=None,
+ negative_prompt_embeds=None,
+ ):
+ if height % 8 != 0 or width % 8 != 0:
+ raise ValueError(f"`height` and `width` have to be divisible by 8 but are {height} and {width}.")
+
+ if callback_on_step_end_tensor_inputs is not None and not all(
+ k in self._callback_tensor_inputs for k in callback_on_step_end_tensor_inputs
+ ):
+ raise ValueError(
+ f"`callback_on_step_end_tensor_inputs` has to be in {self._callback_tensor_inputs}, but found {[k for k in callback_on_step_end_tensor_inputs if k not in self._callback_tensor_inputs]}"
+ )
+ if prompt is not None and prompt_embeds is not None:
+ raise ValueError(
+ f"Cannot forward both `prompt`: {prompt} and `prompt_embeds`: {prompt_embeds}. Please make sure to"
+ " only forward one of the two."
+ )
+ elif prompt is None and prompt_embeds is None:
+ raise ValueError(
+ "Provide either `prompt` or `prompt_embeds`. Cannot leave both `prompt` and `prompt_embeds` undefined."
+ )
+ elif prompt is not None and (not isinstance(prompt, str) and not isinstance(prompt, list)):
+ raise ValueError(f"`prompt` has to be of type `str` or `list` but is {type(prompt)}")
+
+ if prompt is not None and negative_prompt_embeds is not None:
+ raise ValueError(
+ f"Cannot forward both `prompt`: {prompt} and `negative_prompt_embeds`:"
+ f" {negative_prompt_embeds}. Please make sure to only forward one of the two."
+ )
+
+ if negative_prompt is not None and negative_prompt_embeds is not None:
+ raise ValueError(
+ f"Cannot forward both `negative_prompt`: {negative_prompt} and `negative_prompt_embeds`:"
+ f" {negative_prompt_embeds}. Please make sure to only forward one of the two."
+ )
+
+ if prompt_embeds is not None and negative_prompt_embeds is not None:
+ if prompt_embeds.shape != negative_prompt_embeds.shape:
+ raise ValueError(
+ "`prompt_embeds` and `negative_prompt_embeds` must have the same shape when passed directly, but"
+ f" got: `prompt_embeds` {prompt_embeds.shape} != `negative_prompt_embeds`"
+ f" {negative_prompt_embeds.shape}."
+ )
+
+ def fuse_qkv_projections(self) -> None:
+ r"""Enables fused QKV projections."""
+ self.fusing_transformer = True
+ self.transformer.fuse_qkv_projections()
+
+ def unfuse_qkv_projections(self) -> None:
+ r"""Disable QKV projection fusion if enabled."""
+ if not self.fusing_transformer:
+ logger.warning("The Transformer was not initially fused for QKV projections. Doing nothing.")
+ else:
+ self.transformer.unfuse_qkv_projections()
+ self.fusing_transformer = False
+
+ def _prepare_rotary_positional_embeddings(
+ self,
+ height: int,
+ width: int,
+ num_frames: int,
+ device: torch.device,
+ ) -> Tuple[torch.Tensor, torch.Tensor]:
+ grid_height = height // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
+ grid_width = width // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
+ base_size_width = 720 // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
+ base_size_height = 480 // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
+
+ grid_crops_coords = get_resize_crop_region_for_grid(
+ (grid_height, grid_width), base_size_width, base_size_height
+ )
+ freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
+ embed_dim=self.transformer.config.attention_head_dim,
+ crops_coords=grid_crops_coords,
+ grid_size=(grid_height, grid_width),
+ temporal_size=num_frames,
+ use_real=True,
+ )
+
+ freqs_cos = freqs_cos.to(device=device)
+ freqs_sin = freqs_sin.to(device=device)
+ return freqs_cos, freqs_sin
+
+ @property
+ def guidance_scale(self):
+ return self._guidance_scale
+
+ @property
+ def num_timesteps(self):
+ return self._num_timesteps
+
+ @property
+ def interrupt(self):
+ return self._interrupt
+
+ @torch.no_grad()
+ @replace_example_docstring(EXAMPLE_DOC_STRING)
+ def __call__(
+ self,
+ prompt: Optional[Union[str, List[str]]] = None,
+ negative_prompt: Optional[Union[str, List[str]]] = None,
+ height: int = 480,
+ width: int = 720,
+ num_frames: int = 49,
+ num_inference_steps: int = 50,
+ timesteps: Optional[List[int]] = None,
+ guidance_scale: float = 6,
+ use_dynamic_cfg: bool = False,
+ num_videos_per_prompt: int = 1,
+ eta: float = 0.0,
+ generator: Optional[Union[torch.Generator, List[torch.Generator]]] = None,
+ latents: Optional[torch.FloatTensor] = None,
+ prompt_embeds: Optional[torch.FloatTensor] = None,
+ negative_prompt_embeds: Optional[torch.FloatTensor] = None,
+ output_type: str = "numpy",
+ return_dict: bool = False,
+ callback_on_step_end: Optional[
+ Union[Callable[[int, int, Dict], None], PipelineCallback, MultiPipelineCallbacks]
+ ] = None,
+ callback_on_step_end_tensor_inputs: List[str] = ["latents"],
+ max_sequence_length: int = 226,
+ ) -> Union[CogVideoX_FUN_PipelineOutput, Tuple]:
+ """
+ Function invoked when calling the pipeline for generation.
+
+ Args:
+ prompt (`str` or `List[str]`, *optional*):
+ The prompt or prompts to guide the image generation. If not defined, one has to pass `prompt_embeds`.
+ instead.
+ negative_prompt (`str` or `List[str]`, *optional*):
+ The prompt or prompts not to guide the image generation. If not defined, one has to pass
+ `negative_prompt_embeds` instead. Ignored when not using guidance (i.e., ignored if `guidance_scale` is
+ less than `1`).
+ height (`int`, *optional*, defaults to self.unet.config.sample_size * self.vae_scale_factor):
+ The height in pixels of the generated image. This is set to 1024 by default for the best results.
+ width (`int`, *optional*, defaults to self.unet.config.sample_size * self.vae_scale_factor):
+ The width in pixels of the generated image. This is set to 1024 by default for the best results.
+ num_frames (`int`, defaults to `48`):
+ Number of frames to generate. Must be divisible by self.vae_scale_factor_temporal. Generated video will
+ contain 1 extra frame because CogVideoX is conditioned with (num_seconds * fps + 1) frames where
+ num_seconds is 6 and fps is 4. However, since videos can be saved at any fps, the only condition that
+ needs to be satisfied is that of divisibility mentioned above.
+ num_inference_steps (`int`, *optional*, defaults to 50):
+ The number of denoising steps. More denoising steps usually lead to a higher quality image at the
+ expense of slower inference.
+ timesteps (`List[int]`, *optional*):
+ Custom timesteps to use for the denoising process with schedulers which support a `timesteps` argument
+ in their `set_timesteps` method. If not defined, the default behavior when `num_inference_steps` is
+ passed will be used. Must be in descending order.
+ guidance_scale (`float`, *optional*, defaults to 7.0):
+ Guidance scale as defined in [Classifier-Free Diffusion Guidance](https://arxiv.org/abs/2207.12598).
+ `guidance_scale` is defined as `w` of equation 2. of [Imagen
+ Paper](https://arxiv.org/pdf/2205.11487.pdf). Guidance scale is enabled by setting `guidance_scale >
+ 1`. Higher guidance scale encourages to generate images that are closely linked to the text `prompt`,
+ usually at the expense of lower image quality.
+ num_videos_per_prompt (`int`, *optional*, defaults to 1):
+ The number of videos to generate per prompt.
+ generator (`torch.Generator` or `List[torch.Generator]`, *optional*):
+ One or a list of [torch generator(s)](https://pytorch.org/docs/stable/generated/torch.Generator.html)
+ to make generation deterministic.
+ latents (`torch.FloatTensor`, *optional*):
+ Pre-generated noisy latents, sampled from a Gaussian distribution, to be used as inputs for image
+ generation. Can be used to tweak the same generation with different prompts. If not provided, a latents
+ tensor will ge generated by sampling using the supplied random `generator`.
+ prompt_embeds (`torch.FloatTensor`, *optional*):
+ Pre-generated text embeddings. Can be used to easily tweak text inputs, *e.g.* prompt weighting. If not
+ provided, text embeddings will be generated from `prompt` input argument.
+ negative_prompt_embeds (`torch.FloatTensor`, *optional*):
+ Pre-generated negative text embeddings. Can be used to easily tweak text inputs, *e.g.* prompt
+ weighting. If not provided, negative_prompt_embeds will be generated from `negative_prompt` input
+ argument.
+ output_type (`str`, *optional*, defaults to `"pil"`):
+ The output format of the generate image. Choose between
+ [PIL](https://pillow.readthedocs.io/en/stable/): `PIL.Image.Image` or `np.array`.
+ return_dict (`bool`, *optional*, defaults to `True`):
+ Whether or not to return a [`~pipelines.stable_diffusion_xl.StableDiffusionXLPipelineOutput`] instead
+ of a plain tuple.
+ callback_on_step_end (`Callable`, *optional*):
+ A function that calls at the end of each denoising steps during the inference. The function is called
+ with the following arguments: `callback_on_step_end(self: DiffusionPipeline, step: int, timestep: int,
+ callback_kwargs: Dict)`. `callback_kwargs` will include a list of all tensors as specified by
+ `callback_on_step_end_tensor_inputs`.
+ callback_on_step_end_tensor_inputs (`List`, *optional*):
+ The list of tensor inputs for the `callback_on_step_end` function. The tensors specified in the list
+ will be passed as `callback_kwargs` argument. You will only be able to include variables listed in the
+ `._callback_tensor_inputs` attribute of your pipeline class.
+ max_sequence_length (`int`, defaults to `226`):
+ Maximum sequence length in encoded prompt. Must be consistent with
+ `self.transformer.config.max_text_seq_length` otherwise may lead to poor results.
+
+ Examples:
+
+ Returns:
+ [`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_FUN_PipelineOutput`] or `tuple`:
+ [`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_FUN_PipelineOutput`] if `return_dict` is True, otherwise a
+ `tuple`. When returning a tuple, the first element is a list with the generated images.
+ """
+
+ if num_frames > 49:
+ raise ValueError(
+ "The number of frames must be less than 49 for now due to static positional embeddings. This will be updated in the future to remove this limitation."
+ )
+
+ if isinstance(callback_on_step_end, (PipelineCallback, MultiPipelineCallbacks)):
+ callback_on_step_end_tensor_inputs = callback_on_step_end.tensor_inputs
+
+ height = height or self.transformer.config.sample_size * self.vae_scale_factor_spatial
+ width = width or self.transformer.config.sample_size * self.vae_scale_factor_spatial
+ num_videos_per_prompt = 1
+
+ # 1. Check inputs. Raise error if not correct
+ self.check_inputs(
+ prompt,
+ height,
+ width,
+ negative_prompt,
+ callback_on_step_end_tensor_inputs,
+ prompt_embeds,
+ negative_prompt_embeds,
+ )
+ self._guidance_scale = guidance_scale
+ self._interrupt = False
+
+ # 2. Default call parameters
+ if prompt is not None and isinstance(prompt, str):
+ batch_size = 1
+ elif prompt is not None and isinstance(prompt, list):
+ batch_size = len(prompt)
+ else:
+ batch_size = prompt_embeds.shape[0]
+
+ device = self._execution_device
+
+ # here `guidance_scale` is defined analog to the guidance weight `w` of equation (2)
+ # of the Imagen paper: https://arxiv.org/pdf/2205.11487.pdf . `guidance_scale = 1`
+ # corresponds to doing no classifier free guidance.
+ do_classifier_free_guidance = guidance_scale > 1.0
+
+ # 3. Encode input prompt
+ prompt_embeds, negative_prompt_embeds = self.encode_prompt(
+ prompt,
+ negative_prompt,
+ do_classifier_free_guidance,
+ num_videos_per_prompt=num_videos_per_prompt,
+ prompt_embeds=prompt_embeds,
+ negative_prompt_embeds=negative_prompt_embeds,
+ max_sequence_length=max_sequence_length,
+ device=device,
+ )
+ if do_classifier_free_guidance:
+ prompt_embeds = torch.cat([negative_prompt_embeds, prompt_embeds], dim=0)
+
+ # 4. Prepare timesteps
+ timesteps, num_inference_steps = retrieve_timesteps(self.scheduler, num_inference_steps, device, timesteps)
+ self._num_timesteps = len(timesteps)
+
+ # 5. Prepare latents.
+ latent_channels = self.transformer.config.in_channels
+ latents = self.prepare_latents(
+ batch_size * num_videos_per_prompt,
+ latent_channels,
+ num_frames,
+ height,
+ width,
+ prompt_embeds.dtype,
+ device,
+ generator,
+ latents,
+ )
+
+ # 6. Prepare extra step kwargs. TODO: Logic should ideally just be moved out of the pipeline
+ extra_step_kwargs = self.prepare_extra_step_kwargs(generator, eta)
+
+ # 7. Create rotary embeds if required
+ image_rotary_emb = (
+ self._prepare_rotary_positional_embeddings(height, width, latents.size(1), device)
+ if self.transformer.config.use_rotary_positional_embeddings
+ else None
+ )
+
+ # 8. Denoising loop
+ num_warmup_steps = max(len(timesteps) - num_inference_steps * self.scheduler.order, 0)
+
+ with self.progress_bar(total=num_inference_steps) as progress_bar:
+ # for DPM-solver++
+ old_pred_original_sample = None
+ for i, t in enumerate(timesteps):
+ if self.interrupt:
+ continue
+
+ latent_model_input = torch.cat([latents] * 2) if do_classifier_free_guidance else latents
+ latent_model_input = self.scheduler.scale_model_input(latent_model_input, t)
+
+ # broadcast to batch dimension in a way that's compatible with ONNX/Core ML
+ timestep = t.expand(latent_model_input.shape[0])
+
+ # predict noise model_output
+ noise_pred = self.transformer(
+ hidden_states=latent_model_input,
+ encoder_hidden_states=prompt_embeds,
+ timestep=timestep,
+ image_rotary_emb=image_rotary_emb,
+ return_dict=False,
+ )[0]
+ noise_pred = noise_pred.float()
+
+ # perform guidance
+ if use_dynamic_cfg:
+ self._guidance_scale = 1 + guidance_scale * (
+ (1 - math.cos(math.pi * ((num_inference_steps - t.item()) / num_inference_steps) ** 5.0)) / 2
+ )
+ if do_classifier_free_guidance:
+ noise_pred_uncond, noise_pred_text = noise_pred.chunk(2)
+ noise_pred = noise_pred_uncond + self.guidance_scale * (noise_pred_text - noise_pred_uncond)
+
+ # compute the previous noisy sample x_t -> x_t-1
+ if not isinstance(self.scheduler, CogVideoXDPMScheduler):
+ latents = self.scheduler.step(noise_pred, t, latents, **extra_step_kwargs, return_dict=False)[0]
+ else:
+ latents, old_pred_original_sample = self.scheduler.step(
+ noise_pred,
+ old_pred_original_sample,
+ t,
+ timesteps[i - 1] if i > 0 else None,
+ latents,
+ **extra_step_kwargs,
+ return_dict=False,
+ )
+ latents = latents.to(prompt_embeds.dtype)
+
+ # call the callback, if provided
+ if callback_on_step_end is not None:
+ callback_kwargs = {}
+ for k in callback_on_step_end_tensor_inputs:
+ callback_kwargs[k] = locals()[k]
+ callback_outputs = callback_on_step_end(self, i, t, callback_kwargs)
+
+ latents = callback_outputs.pop("latents", latents)
+ prompt_embeds = callback_outputs.pop("prompt_embeds", prompt_embeds)
+ negative_prompt_embeds = callback_outputs.pop("negative_prompt_embeds", negative_prompt_embeds)
+
+ if i == len(timesteps) - 1 or ((i + 1) > num_warmup_steps and (i + 1) % self.scheduler.order == 0):
+ progress_bar.update()
+
+ if output_type == "numpy":
+ video = self.decode_latents(latents)
+ elif not output_type == "latent":
+ video = self.decode_latents(latents)
+ video = self.video_processor.postprocess_video(video=video, output_type=output_type)
+ else:
+ video = latents
+
+ # Offload all models
+ self.maybe_free_model_hooks()
+
+ if not return_dict:
+ video = torch.from_numpy(video)
+
+ return CogVideoX_FUN_PipelineOutput(videos=video)
diff --git a/cogvideox/pipeline/pipeline_cogvideox_inpaint.py b/cogvideox/pipeline/pipeline_cogvideox_inpaint.py
new file mode 100644
index 0000000..f074690
--- /dev/null
+++ b/cogvideox/pipeline/pipeline_cogvideox_inpaint.py
@@ -0,0 +1,1003 @@
+# Copyright 2024 The CogVideoX team, Tsinghua University & ZhipuAI and The HuggingFace Team.
+# All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+import inspect
+import math
+from dataclasses import dataclass
+from typing import Callable, Dict, List, Optional, Tuple, Union
+
+import torch
+import torch.nn.functional as F
+from einops import rearrange
+from transformers import T5EncoderModel, T5Tokenizer
+
+from diffusers.callbacks import MultiPipelineCallbacks, PipelineCallback
+from diffusers.models import AutoencoderKLCogVideoX, CogVideoXTransformer3DModel
+from diffusers.models.embeddings import get_3d_rotary_pos_embed
+from diffusers.pipelines.pipeline_utils import DiffusionPipeline
+from diffusers.schedulers import CogVideoXDDIMScheduler, CogVideoXDPMScheduler
+from diffusers.utils import BaseOutput, logging, replace_example_docstring
+from diffusers.utils.torch_utils import randn_tensor
+from diffusers.video_processor import VideoProcessor
+from diffusers.image_processor import VaeImageProcessor
+from einops import rearrange
+
+
+logger = logging.get_logger(__name__) # pylint: disable=invalid-name
+
+
+EXAMPLE_DOC_STRING = """
+ Examples:
+ ```python
+ >>> import torch
+ >>> from diffusers import CogVideoX_FUN_Pipeline
+ >>> from diffusers.utils import export_to_video
+
+ >>> # Models: "THUDM/CogVideoX-2b" or "THUDM/CogVideoX-5b"
+ >>> pipe = CogVideoX_FUN_Pipeline.from_pretrained("THUDM/CogVideoX-2b", torch_dtype=torch.float16).to("cuda")
+ >>> prompt = (
+ ... "A panda, dressed in a small, red jacket and a tiny hat, sits on a wooden stool in a serene bamboo forest. "
+ ... "The panda's fluffy paws strum a miniature acoustic guitar, producing soft, melodic tunes. Nearby, a few other "
+ ... "pandas gather, watching curiously and some clapping in rhythm. Sunlight filters through the tall bamboo, "
+ ... "casting a gentle glow on the scene. The panda's face is expressive, showing concentration and joy as it plays. "
+ ... "The background includes a small, flowing stream and vibrant green foliage, enhancing the peaceful and magical "
+ ... "atmosphere of this unique musical performance."
+ ... )
+ >>> video = pipe(prompt=prompt, guidance_scale=6, num_inference_steps=50).frames[0]
+ >>> export_to_video(video, "output.mp4", fps=8)
+ ```
+"""
+
+
+# Similar to diffusers.pipelines.hunyuandit.pipeline_hunyuandit.get_resize_crop_region_for_grid
+def get_resize_crop_region_for_grid(src, tgt_width, tgt_height):
+ tw = tgt_width
+ th = tgt_height
+ h, w = src
+ r = h / w
+ if r > (th / tw):
+ resize_height = th
+ resize_width = int(round(th / h * w))
+ else:
+ resize_width = tw
+ resize_height = int(round(tw / w * h))
+
+ crop_top = int(round((th - resize_height) / 2.0))
+ crop_left = int(round((tw - resize_width) / 2.0))
+
+ return (crop_top, crop_left), (crop_top + resize_height, crop_left + resize_width)
+
+
+# Copied from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion.retrieve_timesteps
+def retrieve_timesteps(
+ scheduler,
+ num_inference_steps: Optional[int] = None,
+ device: Optional[Union[str, torch.device]] = None,
+ timesteps: Optional[List[int]] = None,
+ sigmas: Optional[List[float]] = None,
+ **kwargs,
+):
+ """
+ Calls the scheduler's `set_timesteps` method and retrieves timesteps from the scheduler after the call. Handles
+ custom timesteps. Any kwargs will be supplied to `scheduler.set_timesteps`.
+
+ Args:
+ scheduler (`SchedulerMixin`):
+ The scheduler to get timesteps from.
+ num_inference_steps (`int`):
+ The number of diffusion steps used when generating samples with a pre-trained model. If used, `timesteps`
+ must be `None`.
+ device (`str` or `torch.device`, *optional*):
+ The device to which the timesteps should be moved to. If `None`, the timesteps are not moved.
+ timesteps (`List[int]`, *optional*):
+ Custom timesteps used to override the timestep spacing strategy of the scheduler. If `timesteps` is passed,
+ `num_inference_steps` and `sigmas` must be `None`.
+ sigmas (`List[float]`, *optional*):
+ Custom sigmas used to override the timestep spacing strategy of the scheduler. If `sigmas` is passed,
+ `num_inference_steps` and `timesteps` must be `None`.
+
+ Returns:
+ `Tuple[torch.Tensor, int]`: A tuple where the first element is the timestep schedule from the scheduler and the
+ second element is the number of inference steps.
+ """
+ if timesteps is not None and sigmas is not None:
+ raise ValueError("Only one of `timesteps` or `sigmas` can be passed. Please choose one to set custom values")
+ if timesteps is not None:
+ accepts_timesteps = "timesteps" in set(inspect.signature(scheduler.set_timesteps).parameters.keys())
+ if not accepts_timesteps:
+ raise ValueError(
+ f"The current scheduler class {scheduler.__class__}'s `set_timesteps` does not support custom"
+ f" timestep schedules. Please check whether you are using the correct scheduler."
+ )
+ scheduler.set_timesteps(timesteps=timesteps, device=device, **kwargs)
+ timesteps = scheduler.timesteps
+ num_inference_steps = len(timesteps)
+ elif sigmas is not None:
+ accept_sigmas = "sigmas" in set(inspect.signature(scheduler.set_timesteps).parameters.keys())
+ if not accept_sigmas:
+ raise ValueError(
+ f"The current scheduler class {scheduler.__class__}'s `set_timesteps` does not support custom"
+ f" sigmas schedules. Please check whether you are using the correct scheduler."
+ )
+ scheduler.set_timesteps(sigmas=sigmas, device=device, **kwargs)
+ timesteps = scheduler.timesteps
+ num_inference_steps = len(timesteps)
+ else:
+ scheduler.set_timesteps(num_inference_steps, device=device, **kwargs)
+ timesteps = scheduler.timesteps
+ return timesteps, num_inference_steps
+
+
+def resize_mask(mask, latent, process_first_frame_only=True):
+ latent_size = latent.size()
+ batch_size, channels, num_frames, height, width = mask.shape
+
+ if process_first_frame_only:
+ target_size = list(latent_size[2:])
+ target_size[0] = 1
+ first_frame_resized = F.interpolate(
+ mask[:, :, 0:1, :, :],
+ size=target_size,
+ mode='trilinear',
+ align_corners=False
+ )
+
+ target_size = list(latent_size[2:])
+ target_size[0] = target_size[0] - 1
+ if target_size[0] != 0:
+ remaining_frames_resized = F.interpolate(
+ mask[:, :, 1:, :, :],
+ size=target_size,
+ mode='trilinear',
+ align_corners=False
+ )
+ resized_mask = torch.cat([first_frame_resized, remaining_frames_resized], dim=2)
+ else:
+ resized_mask = first_frame_resized
+ else:
+ target_size = list(latent_size[2:])
+ resized_mask = F.interpolate(
+ mask,
+ size=target_size,
+ mode='trilinear',
+ align_corners=False
+ )
+ return resized_mask
+
+
+@dataclass
+class CogVideoX_FUN_PipelineOutput(BaseOutput):
+ r"""
+ Output class for CogVideo pipelines.
+
+ Args:
+ video (`torch.Tensor`, `np.ndarray`, or List[List[PIL.Image.Image]]):
+ List of video outputs - It can be a nested list of length `batch_size,` with each sub-list containing
+ denoised PIL image sequences of length `num_frames.` It can also be a NumPy array or Torch tensor of shape
+ `(batch_size, num_frames, channels, height, width)`.
+ """
+
+ videos: torch.Tensor
+
+
+class CogVideoX_FUN_Pipeline_Inpaint(DiffusionPipeline):
+ r"""
+ Pipeline for text-to-video generation using CogVideoX.
+
+ This model inherits from [`DiffusionPipeline`]. Check the superclass documentation for the generic methods the
+ library implements for all the pipelines (such as downloading or saving, running on a particular device, etc.)
+
+ Args:
+ vae ([`AutoencoderKL`]):
+ Variational Auto-Encoder (VAE) Model to encode and decode videos to and from latent representations.
+ text_encoder ([`T5EncoderModel`]):
+ Frozen text-encoder. CogVideoX_FUN uses
+ [T5](https://huggingface.co/docs/transformers/model_doc/t5#transformers.T5EncoderModel); specifically the
+ [t5-v1_1-xxl](https://huggingface.co/PixArt-alpha/PixArt-alpha/tree/main/t5-v1_1-xxl) variant.
+ tokenizer (`T5Tokenizer`):
+ Tokenizer of class
+ [T5Tokenizer](https://huggingface.co/docs/transformers/model_doc/t5#transformers.T5Tokenizer).
+ transformer ([`CogVideoXTransformer3DModel`]):
+ A text conditioned `CogVideoXTransformer3DModel` to denoise the encoded video latents.
+ scheduler ([`SchedulerMixin`]):
+ A scheduler to be used in combination with `transformer` to denoise the encoded video latents.
+ """
+
+ _optional_components = []
+ model_cpu_offload_seq = "text_encoder->vae->transformer->vae"
+
+ _callback_tensor_inputs = [
+ "latents",
+ "prompt_embeds",
+ "negative_prompt_embeds",
+ ]
+
+ def __init__(
+ self,
+ tokenizer: T5Tokenizer,
+ text_encoder: T5EncoderModel,
+ vae: AutoencoderKLCogVideoX,
+ transformer: CogVideoXTransformer3DModel,
+ scheduler: Union[CogVideoXDDIMScheduler, CogVideoXDPMScheduler],
+ ):
+ super().__init__()
+
+ self.register_modules(
+ tokenizer=tokenizer, text_encoder=text_encoder, vae=vae, transformer=transformer, scheduler=scheduler
+ )
+ self.vae_scale_factor_spatial = (
+ 2 ** (len(self.vae.config.block_out_channels) - 1) if hasattr(self, "vae") and self.vae is not None else 8
+ )
+ self.vae_scale_factor_temporal = (
+ self.vae.config.temporal_compression_ratio if hasattr(self, "vae") and self.vae is not None else 4
+ )
+
+ self.video_processor = VideoProcessor(vae_scale_factor=self.vae_scale_factor_spatial)
+
+ self.vae_scale_factor = 2 ** (len(self.vae.config.block_out_channels) - 1)
+ self.image_processor = VaeImageProcessor(vae_scale_factor=self.vae_scale_factor)
+ self.mask_processor = VaeImageProcessor(
+ vae_scale_factor=self.vae_scale_factor, do_normalize=False, do_binarize=True, do_convert_grayscale=True
+ )
+
+ def _get_t5_prompt_embeds(
+ self,
+ prompt: Union[str, List[str]] = None,
+ num_videos_per_prompt: int = 1,
+ max_sequence_length: int = 226,
+ device: Optional[torch.device] = None,
+ dtype: Optional[torch.dtype] = None,
+ ):
+ device = device or self._execution_device
+ dtype = dtype or self.text_encoder.dtype
+
+ prompt = [prompt] if isinstance(prompt, str) else prompt
+ batch_size = len(prompt)
+
+ text_inputs = self.tokenizer(
+ prompt,
+ padding="max_length",
+ max_length=max_sequence_length,
+ truncation=True,
+ add_special_tokens=True,
+ return_tensors="pt",
+ )
+ text_input_ids = text_inputs.input_ids
+ untruncated_ids = self.tokenizer(prompt, padding="longest", return_tensors="pt").input_ids
+
+ if untruncated_ids.shape[-1] >= text_input_ids.shape[-1] and not torch.equal(text_input_ids, untruncated_ids):
+ removed_text = self.tokenizer.batch_decode(untruncated_ids[:, max_sequence_length - 1 : -1])
+ logger.warning(
+ "The following part of your input was truncated because `max_sequence_length` is set to "
+ f" {max_sequence_length} tokens: {removed_text}"
+ )
+
+ prompt_embeds = self.text_encoder(text_input_ids.to(device))[0]
+ prompt_embeds = prompt_embeds.to(dtype=dtype, device=device)
+
+ # duplicate text embeddings for each generation per prompt, using mps friendly method
+ _, seq_len, _ = prompt_embeds.shape
+ prompt_embeds = prompt_embeds.repeat(1, num_videos_per_prompt, 1)
+ prompt_embeds = prompt_embeds.view(batch_size * num_videos_per_prompt, seq_len, -1)
+
+ return prompt_embeds
+
+ def encode_prompt(
+ self,
+ prompt: Union[str, List[str]],
+ negative_prompt: Optional[Union[str, List[str]]] = None,
+ do_classifier_free_guidance: bool = True,
+ num_videos_per_prompt: int = 1,
+ prompt_embeds: Optional[torch.Tensor] = None,
+ negative_prompt_embeds: Optional[torch.Tensor] = None,
+ max_sequence_length: int = 226,
+ device: Optional[torch.device] = None,
+ dtype: Optional[torch.dtype] = None,
+ ):
+ r"""
+ Encodes the prompt into text encoder hidden states.
+
+ Args:
+ prompt (`str` or `List[str]`, *optional*):
+ prompt to be encoded
+ negative_prompt (`str` or `List[str]`, *optional*):
+ The prompt or prompts not to guide the image generation. If not defined, one has to pass
+ `negative_prompt_embeds` instead. Ignored when not using guidance (i.e., ignored if `guidance_scale` is
+ less than `1`).
+ do_classifier_free_guidance (`bool`, *optional*, defaults to `True`):
+ Whether to use classifier free guidance or not.
+ num_videos_per_prompt (`int`, *optional*, defaults to 1):
+ Number of videos that should be generated per prompt. torch device to place the resulting embeddings on
+ prompt_embeds (`torch.Tensor`, *optional*):
+ Pre-generated text embeddings. Can be used to easily tweak text inputs, *e.g.* prompt weighting. If not
+ provided, text embeddings will be generated from `prompt` input argument.
+ negative_prompt_embeds (`torch.Tensor`, *optional*):
+ Pre-generated negative text embeddings. Can be used to easily tweak text inputs, *e.g.* prompt
+ weighting. If not provided, negative_prompt_embeds will be generated from `negative_prompt` input
+ argument.
+ device: (`torch.device`, *optional*):
+ torch device
+ dtype: (`torch.dtype`, *optional*):
+ torch dtype
+ """
+ device = device or self._execution_device
+
+ prompt = [prompt] if isinstance(prompt, str) else prompt
+ if prompt is not None:
+ batch_size = len(prompt)
+ else:
+ batch_size = prompt_embeds.shape[0]
+
+ if prompt_embeds is None:
+ prompt_embeds = self._get_t5_prompt_embeds(
+ prompt=prompt,
+ num_videos_per_prompt=num_videos_per_prompt,
+ max_sequence_length=max_sequence_length,
+ device=device,
+ dtype=dtype,
+ )
+
+ if do_classifier_free_guidance and negative_prompt_embeds is None:
+ negative_prompt = negative_prompt or ""
+ negative_prompt = batch_size * [negative_prompt] if isinstance(negative_prompt, str) else negative_prompt
+
+ if prompt is not None and type(prompt) is not type(negative_prompt):
+ raise TypeError(
+ f"`negative_prompt` should be the same type to `prompt`, but got {type(negative_prompt)} !="
+ f" {type(prompt)}."
+ )
+ elif batch_size != len(negative_prompt):
+ raise ValueError(
+ f"`negative_prompt`: {negative_prompt} has batch size {len(negative_prompt)}, but `prompt`:"
+ f" {prompt} has batch size {batch_size}. Please make sure that passed `negative_prompt` matches"
+ " the batch size of `prompt`."
+ )
+
+ negative_prompt_embeds = self._get_t5_prompt_embeds(
+ prompt=negative_prompt,
+ num_videos_per_prompt=num_videos_per_prompt,
+ max_sequence_length=max_sequence_length,
+ device=device,
+ dtype=dtype,
+ )
+
+ return prompt_embeds, negative_prompt_embeds
+
+ def prepare_latents(
+ self,
+ batch_size,
+ num_channels_latents,
+ height,
+ width,
+ video_length,
+ dtype,
+ device,
+ generator,
+ latents=None,
+ video=None,
+ timestep=None,
+ is_strength_max=True,
+ return_noise=False,
+ return_video_latents=False,
+ ):
+ shape = (
+ batch_size,
+ (video_length - 1) // self.vae_scale_factor_temporal + 1,
+ num_channels_latents,
+ height // self.vae_scale_factor_spatial,
+ width // self.vae_scale_factor_spatial,
+ )
+ if isinstance(generator, list) and len(generator) != batch_size:
+ raise ValueError(
+ f"You have passed a list of generators of length {len(generator)}, but requested an effective batch"
+ f" size of {batch_size}. Make sure the batch size matches the length of the generators."
+ )
+
+ if return_video_latents or (latents is None and not is_strength_max):
+ video = video.to(device=device, dtype=self.vae.dtype)
+
+ bs = 1
+ new_video = []
+ for i in range(0, video.shape[0], bs):
+ video_bs = video[i : i + bs]
+ video_bs = self.vae.encode(video_bs)[0]
+ video_bs = video_bs.sample()
+ new_video.append(video_bs)
+ video = torch.cat(new_video, dim = 0)
+ video = video * self.vae.config.scaling_factor
+
+ video_latents = video.repeat(batch_size // video.shape[0], 1, 1, 1, 1)
+ video_latents = video_latents.to(device=device, dtype=dtype)
+ video_latents = rearrange(video_latents, "b c f h w -> b f c h w")
+
+ if latents is None:
+ noise = randn_tensor(shape, generator=generator, device=device, dtype=dtype)
+ # if strength is 1. then initialise the latents to noise, else initial to image + noise
+ latents = noise if is_strength_max else self.scheduler.add_noise(video_latents, noise, timestep)
+ # if pure noise then scale the initial latents by the Scheduler's init sigma
+ latents = latents * self.scheduler.init_noise_sigma if is_strength_max else latents
+ else:
+ noise = latents.to(device)
+ latents = noise * self.scheduler.init_noise_sigma
+
+ # scale the initial noise by the standard deviation required by the scheduler
+ outputs = (latents,)
+
+ if return_noise:
+ outputs += (noise,)
+
+ if return_video_latents:
+ outputs += (video_latents,)
+
+ return outputs
+
+ def prepare_mask_latents(
+ self, mask, masked_image, batch_size, height, width, dtype, device, generator, do_classifier_free_guidance
+ ):
+ # resize the mask to latents shape as we concatenate the mask to the latents
+ # we do that before converting to dtype to avoid breaking in case we're using cpu_offload
+ # and half precision
+
+ if mask is not None:
+ mask = mask.to(device=device, dtype=self.vae.dtype)
+ bs = 1
+ new_mask = []
+ for i in range(0, mask.shape[0], bs):
+ mask_bs = mask[i : i + bs]
+ mask_bs = self.vae.encode(mask_bs)[0]
+ mask_bs = mask_bs.mode()
+ new_mask.append(mask_bs)
+ mask = torch.cat(new_mask, dim = 0)
+ mask = mask * self.vae.config.scaling_factor
+
+ if masked_image is not None:
+ masked_image = masked_image.to(device=device, dtype=self.vae.dtype)
+ bs = 1
+ new_mask_pixel_values = []
+ for i in range(0, masked_image.shape[0], bs):
+ mask_pixel_values_bs = masked_image[i : i + bs]
+ mask_pixel_values_bs = self.vae.encode(mask_pixel_values_bs)[0]
+ mask_pixel_values_bs = mask_pixel_values_bs.mode()
+ new_mask_pixel_values.append(mask_pixel_values_bs)
+ masked_image_latents = torch.cat(new_mask_pixel_values, dim = 0)
+ masked_image_latents = masked_image_latents * self.vae.config.scaling_factor
+ else:
+ masked_image_latents = None
+
+ return mask, masked_image_latents
+
+ def decode_latents(self, latents: torch.Tensor) -> torch.Tensor:
+ latents = latents.permute(0, 2, 1, 3, 4) # [batch_size, num_channels, num_frames, height, width]
+ latents = 1 / self.vae.config.scaling_factor * latents
+
+ frames = self.vae.decode(latents).sample
+ frames = (frames / 2 + 0.5).clamp(0, 1)
+ # we always cast to float32 as this does not cause significant overhead and is compatible with bfloa16
+ frames = frames.cpu().float().numpy()
+ return frames
+
+ # Copied from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion.StableDiffusionPipeline.prepare_extra_step_kwargs
+ def prepare_extra_step_kwargs(self, generator, eta):
+ # prepare extra kwargs for the scheduler step, since not all schedulers have the same signature
+ # eta (η) is only used with the DDIMScheduler, it will be ignored for other schedulers.
+ # eta corresponds to η in DDIM paper: https://arxiv.org/abs/2010.02502
+ # and should be between [0, 1]
+
+ accepts_eta = "eta" in set(inspect.signature(self.scheduler.step).parameters.keys())
+ extra_step_kwargs = {}
+ if accepts_eta:
+ extra_step_kwargs["eta"] = eta
+
+ # check if the scheduler accepts generator
+ accepts_generator = "generator" in set(inspect.signature(self.scheduler.step).parameters.keys())
+ if accepts_generator:
+ extra_step_kwargs["generator"] = generator
+ return extra_step_kwargs
+
+ # Copied from diffusers.pipelines.latte.pipeline_latte.LattePipeline.check_inputs
+ def check_inputs(
+ self,
+ prompt,
+ height,
+ width,
+ negative_prompt,
+ callback_on_step_end_tensor_inputs,
+ prompt_embeds=None,
+ negative_prompt_embeds=None,
+ ):
+ if height % 8 != 0 or width % 8 != 0:
+ raise ValueError(f"`height` and `width` have to be divisible by 8 but are {height} and {width}.")
+
+ if callback_on_step_end_tensor_inputs is not None and not all(
+ k in self._callback_tensor_inputs for k in callback_on_step_end_tensor_inputs
+ ):
+ raise ValueError(
+ f"`callback_on_step_end_tensor_inputs` has to be in {self._callback_tensor_inputs}, but found {[k for k in callback_on_step_end_tensor_inputs if k not in self._callback_tensor_inputs]}"
+ )
+ if prompt is not None and prompt_embeds is not None:
+ raise ValueError(
+ f"Cannot forward both `prompt`: {prompt} and `prompt_embeds`: {prompt_embeds}. Please make sure to"
+ " only forward one of the two."
+ )
+ elif prompt is None and prompt_embeds is None:
+ raise ValueError(
+ "Provide either `prompt` or `prompt_embeds`. Cannot leave both `prompt` and `prompt_embeds` undefined."
+ )
+ elif prompt is not None and (not isinstance(prompt, str) and not isinstance(prompt, list)):
+ raise ValueError(f"`prompt` has to be of type `str` or `list` but is {type(prompt)}")
+
+ if prompt is not None and negative_prompt_embeds is not None:
+ raise ValueError(
+ f"Cannot forward both `prompt`: {prompt} and `negative_prompt_embeds`:"
+ f" {negative_prompt_embeds}. Please make sure to only forward one of the two."
+ )
+
+ if negative_prompt is not None and negative_prompt_embeds is not None:
+ raise ValueError(
+ f"Cannot forward both `negative_prompt`: {negative_prompt} and `negative_prompt_embeds`:"
+ f" {negative_prompt_embeds}. Please make sure to only forward one of the two."
+ )
+
+ if prompt_embeds is not None and negative_prompt_embeds is not None:
+ if prompt_embeds.shape != negative_prompt_embeds.shape:
+ raise ValueError(
+ "`prompt_embeds` and `negative_prompt_embeds` must have the same shape when passed directly, but"
+ f" got: `prompt_embeds` {prompt_embeds.shape} != `negative_prompt_embeds`"
+ f" {negative_prompt_embeds.shape}."
+ )
+
+ def fuse_qkv_projections(self) -> None:
+ r"""Enables fused QKV projections."""
+ self.fusing_transformer = True
+ self.transformer.fuse_qkv_projections()
+
+ def unfuse_qkv_projections(self) -> None:
+ r"""Disable QKV projection fusion if enabled."""
+ if not self.fusing_transformer:
+ logger.warning("The Transformer was not initially fused for QKV projections. Doing nothing.")
+ else:
+ self.transformer.unfuse_qkv_projections()
+ self.fusing_transformer = False
+
+ def _prepare_rotary_positional_embeddings(
+ self,
+ height: int,
+ width: int,
+ num_frames: int,
+ device: torch.device,
+ ) -> Tuple[torch.Tensor, torch.Tensor]:
+ grid_height = height // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
+ grid_width = width // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
+ base_size_width = 720 // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
+ base_size_height = 480 // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
+
+ grid_crops_coords = get_resize_crop_region_for_grid(
+ (grid_height, grid_width), base_size_width, base_size_height
+ )
+ freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
+ embed_dim=self.transformer.config.attention_head_dim,
+ crops_coords=grid_crops_coords,
+ grid_size=(grid_height, grid_width),
+ temporal_size=num_frames,
+ use_real=True,
+ )
+
+ freqs_cos = freqs_cos.to(device=device)
+ freqs_sin = freqs_sin.to(device=device)
+ return freqs_cos, freqs_sin
+
+ @property
+ def guidance_scale(self):
+ return self._guidance_scale
+
+ @property
+ def num_timesteps(self):
+ return self._num_timesteps
+
+ @property
+ def interrupt(self):
+ return self._interrupt
+
+ # Copied from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion_img2img.StableDiffusionImg2ImgPipeline.get_timesteps
+ def get_timesteps(self, num_inference_steps, strength, device):
+ # get the original timestep using init_timestep
+ init_timestep = min(int(num_inference_steps * strength), num_inference_steps)
+
+ t_start = max(num_inference_steps - init_timestep, 0)
+ timesteps = self.scheduler.timesteps[t_start * self.scheduler.order :]
+
+ return timesteps, num_inference_steps - t_start
+
+ @torch.no_grad()
+ @replace_example_docstring(EXAMPLE_DOC_STRING)
+ def __call__(
+ self,
+ prompt: Optional[Union[str, List[str]]] = None,
+ negative_prompt: Optional[Union[str, List[str]]] = None,
+ height: int = 480,
+ width: int = 720,
+ video: Union[torch.FloatTensor] = None,
+ mask_video: Union[torch.FloatTensor] = None,
+ masked_video_latents: Union[torch.FloatTensor] = None,
+ num_frames: int = 49,
+ num_inference_steps: int = 50,
+ timesteps: Optional[List[int]] = None,
+ guidance_scale: float = 6,
+ use_dynamic_cfg: bool = False,
+ num_videos_per_prompt: int = 1,
+ eta: float = 0.0,
+ generator: Optional[Union[torch.Generator, List[torch.Generator]]] = None,
+ latents: Optional[torch.FloatTensor] = None,
+ prompt_embeds: Optional[torch.FloatTensor] = None,
+ negative_prompt_embeds: Optional[torch.FloatTensor] = None,
+ output_type: str = "numpy",
+ return_dict: bool = False,
+ callback_on_step_end: Optional[
+ Union[Callable[[int, int, Dict], None], PipelineCallback, MultiPipelineCallbacks]
+ ] = None,
+ callback_on_step_end_tensor_inputs: List[str] = ["latents"],
+ max_sequence_length: int = 226,
+ strength: float = 1,
+ comfyui_progressbar: bool = False,
+ ) -> Union[CogVideoX_FUN_PipelineOutput, Tuple]:
+ """
+ Function invoked when calling the pipeline for generation.
+
+ Args:
+ prompt (`str` or `List[str]`, *optional*):
+ The prompt or prompts to guide the image generation. If not defined, one has to pass `prompt_embeds`.
+ instead.
+ negative_prompt (`str` or `List[str]`, *optional*):
+ The prompt or prompts not to guide the image generation. If not defined, one has to pass
+ `negative_prompt_embeds` instead. Ignored when not using guidance (i.e., ignored if `guidance_scale` is
+ less than `1`).
+ height (`int`, *optional*, defaults to self.unet.config.sample_size * self.vae_scale_factor):
+ The height in pixels of the generated image. This is set to 1024 by default for the best results.
+ width (`int`, *optional*, defaults to self.unet.config.sample_size * self.vae_scale_factor):
+ The width in pixels of the generated image. This is set to 1024 by default for the best results.
+ num_frames (`int`, defaults to `48`):
+ Number of frames to generate. Must be divisible by self.vae_scale_factor_temporal. Generated video will
+ contain 1 extra frame because CogVideoX_FUN is conditioned with (num_seconds * fps + 1) frames where
+ num_seconds is 6 and fps is 4. However, since videos can be saved at any fps, the only condition that
+ needs to be satisfied is that of divisibility mentioned above.
+ num_inference_steps (`int`, *optional*, defaults to 50):
+ The number of denoising steps. More denoising steps usually lead to a higher quality image at the
+ expense of slower inference.
+ timesteps (`List[int]`, *optional*):
+ Custom timesteps to use for the denoising process with schedulers which support a `timesteps` argument
+ in their `set_timesteps` method. If not defined, the default behavior when `num_inference_steps` is
+ passed will be used. Must be in descending order.
+ guidance_scale (`float`, *optional*, defaults to 7.0):
+ Guidance scale as defined in [Classifier-Free Diffusion Guidance](https://arxiv.org/abs/2207.12598).
+ `guidance_scale` is defined as `w` of equation 2. of [Imagen
+ Paper](https://arxiv.org/pdf/2205.11487.pdf). Guidance scale is enabled by setting `guidance_scale >
+ 1`. Higher guidance scale encourages to generate images that are closely linked to the text `prompt`,
+ usually at the expense of lower image quality.
+ num_videos_per_prompt (`int`, *optional*, defaults to 1):
+ The number of videos to generate per prompt.
+ generator (`torch.Generator` or `List[torch.Generator]`, *optional*):
+ One or a list of [torch generator(s)](https://pytorch.org/docs/stable/generated/torch.Generator.html)
+ to make generation deterministic.
+ latents (`torch.FloatTensor`, *optional*):
+ Pre-generated noisy latents, sampled from a Gaussian distribution, to be used as inputs for image
+ generation. Can be used to tweak the same generation with different prompts. If not provided, a latents
+ tensor will ge generated by sampling using the supplied random `generator`.
+ prompt_embeds (`torch.FloatTensor`, *optional*):
+ Pre-generated text embeddings. Can be used to easily tweak text inputs, *e.g.* prompt weighting. If not
+ provided, text embeddings will be generated from `prompt` input argument.
+ negative_prompt_embeds (`torch.FloatTensor`, *optional*):
+ Pre-generated negative text embeddings. Can be used to easily tweak text inputs, *e.g.* prompt
+ weighting. If not provided, negative_prompt_embeds will be generated from `negative_prompt` input
+ argument.
+ output_type (`str`, *optional*, defaults to `"pil"`):
+ The output format of the generate image. Choose between
+ [PIL](https://pillow.readthedocs.io/en/stable/): `PIL.Image.Image` or `np.array`.
+ return_dict (`bool`, *optional*, defaults to `True`):
+ Whether or not to return a [`~pipelines.stable_diffusion_xl.StableDiffusionXLPipelineOutput`] instead
+ of a plain tuple.
+ callback_on_step_end (`Callable`, *optional*):
+ A function that calls at the end of each denoising steps during the inference. The function is called
+ with the following arguments: `callback_on_step_end(self: DiffusionPipeline, step: int, timestep: int,
+ callback_kwargs: Dict)`. `callback_kwargs` will include a list of all tensors as specified by
+ `callback_on_step_end_tensor_inputs`.
+ callback_on_step_end_tensor_inputs (`List`, *optional*):
+ The list of tensor inputs for the `callback_on_step_end` function. The tensors specified in the list
+ will be passed as `callback_kwargs` argument. You will only be able to include variables listed in the
+ `._callback_tensor_inputs` attribute of your pipeline class.
+ max_sequence_length (`int`, defaults to `226`):
+ Maximum sequence length in encoded prompt. Must be consistent with
+ `self.transformer.config.max_text_seq_length` otherwise may lead to poor results.
+
+ Examples:
+
+ Returns:
+ [`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_FUN_PipelineOutput`] or `tuple`:
+ [`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_FUN_PipelineOutput`] if `return_dict` is True, otherwise a
+ `tuple`. When returning a tuple, the first element is a list with the generated images.
+ """
+
+ if num_frames > 49:
+ raise ValueError(
+ "The number of frames must be less than 49 for now due to static positional embeddings. This will be updated in the future to remove this limitation."
+ )
+
+ if isinstance(callback_on_step_end, (PipelineCallback, MultiPipelineCallbacks)):
+ callback_on_step_end_tensor_inputs = callback_on_step_end.tensor_inputs
+
+ height = height or self.transformer.config.sample_size * self.vae_scale_factor_spatial
+ width = width or self.transformer.config.sample_size * self.vae_scale_factor_spatial
+ num_videos_per_prompt = 1
+
+ # 1. Check inputs. Raise error if not correct
+ self.check_inputs(
+ prompt,
+ height,
+ width,
+ negative_prompt,
+ callback_on_step_end_tensor_inputs,
+ prompt_embeds,
+ negative_prompt_embeds,
+ )
+ self._guidance_scale = guidance_scale
+ self._interrupt = False
+
+ # 2. Default call parameters
+ if prompt is not None and isinstance(prompt, str):
+ batch_size = 1
+ elif prompt is not None and isinstance(prompt, list):
+ batch_size = len(prompt)
+ else:
+ batch_size = prompt_embeds.shape[0]
+
+ device = self._execution_device
+
+ # here `guidance_scale` is defined analog to the guidance weight `w` of equation (2)
+ # of the Imagen paper: https://arxiv.org/pdf/2205.11487.pdf . `guidance_scale = 1`
+ # corresponds to doing no classifier free guidance.
+ do_classifier_free_guidance = guidance_scale > 1.0
+
+ # 3. Encode input prompt
+ prompt_embeds, negative_prompt_embeds = self.encode_prompt(
+ prompt,
+ negative_prompt,
+ do_classifier_free_guidance,
+ num_videos_per_prompt=num_videos_per_prompt,
+ prompt_embeds=prompt_embeds,
+ negative_prompt_embeds=negative_prompt_embeds,
+ max_sequence_length=max_sequence_length,
+ device=device,
+ )
+ if do_classifier_free_guidance:
+ prompt_embeds = torch.cat([negative_prompt_embeds, prompt_embeds], dim=0)
+
+ # 4. set timesteps
+ self.scheduler.set_timesteps(num_inference_steps, device=device)
+ timesteps, num_inference_steps = self.get_timesteps(
+ num_inference_steps=num_inference_steps, strength=strength, device=device
+ )
+ self._num_timesteps = len(timesteps)
+ if comfyui_progressbar:
+ from comfy.utils import ProgressBar
+ pbar = ProgressBar(num_inference_steps + 2)
+ # at which timestep to set the initial noise (n.b. 50% if strength is 0.5)
+ latent_timestep = timesteps[:1].repeat(batch_size * num_videos_per_prompt)
+ # create a boolean to check if the strength is set to 1. if so then initialise the latents with pure noise
+ is_strength_max = strength == 1.0
+
+ # 5. Prepare latents.
+ if video is not None:
+ video_length = video.shape[2]
+ init_video = self.image_processor.preprocess(rearrange(video, "b c f h w -> (b f) c h w"), height=height, width=width)
+ init_video = init_video.to(dtype=torch.float32)
+ init_video = rearrange(init_video, "(b f) c h w -> b c f h w", f=video_length)
+ else:
+ init_video = None
+
+ num_channels_latents = self.vae.config.latent_channels
+ num_channels_transformer = self.transformer.config.in_channels
+ return_image_latents = num_channels_transformer == num_channels_latents
+
+ latents_outputs = self.prepare_latents(
+ batch_size * num_videos_per_prompt,
+ num_channels_latents,
+ height,
+ width,
+ video_length,
+ prompt_embeds.dtype,
+ device,
+ generator,
+ latents,
+ video=init_video,
+ timestep=latent_timestep,
+ is_strength_max=is_strength_max,
+ return_noise=True,
+ return_video_latents=return_image_latents,
+ )
+ if return_image_latents:
+ latents, noise, image_latents = latents_outputs
+ else:
+ latents, noise = latents_outputs
+ if comfyui_progressbar:
+ pbar.update(1)
+
+ if mask_video is not None:
+ if (mask_video == 255).all():
+ mask_latents = torch.zeros_like(latents)[:, :, :1].to(latents.device, latents.dtype)
+ masked_video_latents = torch.zeros_like(latents).to(latents.device, latents.dtype)
+
+ mask_input = torch.cat([mask_latents] * 2) if do_classifier_free_guidance else mask_latents
+ masked_video_latents_input = (
+ torch.cat([masked_video_latents] * 2) if do_classifier_free_guidance else masked_video_latents
+ )
+ inpaint_latents = torch.cat([mask_input, masked_video_latents_input], dim=2).to(latents.dtype)
+ else:
+ # Prepare mask latent variables
+ video_length = video.shape[2]
+ mask_condition = self.mask_processor.preprocess(rearrange(mask_video, "b c f h w -> (b f) c h w"), height=height, width=width)
+ mask_condition = mask_condition.to(dtype=torch.float32)
+ mask_condition = rearrange(mask_condition, "(b f) c h w -> b c f h w", f=video_length)
+
+ if num_channels_transformer != num_channels_latents:
+ mask_condition_tile = torch.tile(mask_condition, [1, 3, 1, 1, 1])
+ if masked_video_latents is None:
+ masked_video = init_video * (mask_condition_tile < 0.5) + torch.ones_like(init_video) * (mask_condition_tile > 0.5) * -1
+ else:
+ masked_video = masked_video_latents
+
+ _, masked_video_latents = self.prepare_mask_latents(
+ None,
+ masked_video,
+ batch_size,
+ height,
+ width,
+ prompt_embeds.dtype,
+ device,
+ generator,
+ do_classifier_free_guidance,
+ )
+ mask_latents = resize_mask(1 - mask_condition, masked_video_latents)
+ mask_latents = mask_latents.to(masked_video_latents.device) * self.vae.config.scaling_factor
+
+ mask = torch.tile(mask_condition, [1, num_channels_latents, 1, 1, 1])
+ mask = F.interpolate(mask, size=latents.size()[-3:], mode='trilinear', align_corners=True).to(latents.device, latents.dtype)
+
+ mask_input = torch.cat([mask_latents] * 2) if do_classifier_free_guidance else mask_latents
+ masked_video_latents_input = (
+ torch.cat([masked_video_latents] * 2) if do_classifier_free_guidance else masked_video_latents
+ )
+
+ mask = rearrange(mask, "b c f h w -> b f c h w")
+ mask_input = rearrange(mask_input, "b c f h w -> b f c h w")
+ masked_video_latents_input = rearrange(masked_video_latents_input, "b c f h w -> b f c h w")
+
+ inpaint_latents = torch.cat([mask_input, masked_video_latents_input], dim=2).to(latents.dtype)
+ else:
+ mask = torch.tile(mask_condition, [1, num_channels_latents, 1, 1, 1])
+ mask = F.interpolate(mask, size=latents.size()[-3:], mode='trilinear', align_corners=True).to(latents.device, latents.dtype)
+ mask = rearrange(mask, "b c f h w -> b f c h w")
+
+ inpaint_latents = None
+ else:
+ if num_channels_transformer != num_channels_latents:
+ mask = torch.zeros_like(latents).to(latents.device, latents.dtype)
+ masked_video_latents = torch.zeros_like(latents).to(latents.device, latents.dtype)
+
+ mask_input = torch.cat([mask] * 2) if do_classifier_free_guidance else mask
+ masked_video_latents_input = (
+ torch.cat([masked_video_latents] * 2) if do_classifier_free_guidance else masked_video_latents
+ )
+ inpaint_latents = torch.cat([mask_input, masked_video_latents_input], dim=1).to(latents.dtype)
+ else:
+ mask = torch.zeros_like(init_video[:, :1])
+ mask = torch.tile(mask, [1, num_channels_latents, 1, 1, 1])
+ mask = F.interpolate(mask, size=latents.size()[-3:], mode='trilinear', align_corners=True).to(latents.device, latents.dtype)
+ mask = rearrange(mask, "b c f h w -> b f c h w")
+
+ inpaint_latents = None
+ if comfyui_progressbar:
+ pbar.update(1)
+
+ # 6. Prepare extra step kwargs. TODO: Logic should ideally just be moved out of the pipeline
+ extra_step_kwargs = self.prepare_extra_step_kwargs(generator, eta)
+
+ # 7. Create rotary embeds if required
+ image_rotary_emb = (
+ self._prepare_rotary_positional_embeddings(height, width, latents.size(1), device)
+ if self.transformer.config.use_rotary_positional_embeddings
+ else None
+ )
+
+ # 8. Denoising loop
+ num_warmup_steps = max(len(timesteps) - num_inference_steps * self.scheduler.order, 0)
+
+ with self.progress_bar(total=num_inference_steps) as progress_bar:
+ # for DPM-solver++
+ old_pred_original_sample = None
+ for i, t in enumerate(timesteps):
+ if self.interrupt:
+ continue
+
+ latent_model_input = torch.cat([latents] * 2) if do_classifier_free_guidance else latents
+ latent_model_input = self.scheduler.scale_model_input(latent_model_input, t)
+
+ # broadcast to batch dimension in a way that's compatible with ONNX/Core ML
+ timestep = t.expand(latent_model_input.shape[0])
+
+ # predict noise model_output
+ noise_pred = self.transformer(
+ hidden_states=latent_model_input,
+ encoder_hidden_states=prompt_embeds,
+ timestep=timestep,
+ image_rotary_emb=image_rotary_emb,
+ return_dict=False,
+ inpaint_latents=inpaint_latents,
+ )[0]
+ noise_pred = noise_pred.float()
+
+ # perform guidance
+ if use_dynamic_cfg:
+ self._guidance_scale = 1 + guidance_scale * (
+ (1 - math.cos(math.pi * ((num_inference_steps - t.item()) / num_inference_steps) ** 5.0)) / 2
+ )
+ if do_classifier_free_guidance:
+ noise_pred_uncond, noise_pred_text = noise_pred.chunk(2)
+ noise_pred = noise_pred_uncond + self.guidance_scale * (noise_pred_text - noise_pred_uncond)
+
+ # compute the previous noisy sample x_t -> x_t-1
+ if not isinstance(self.scheduler, CogVideoXDPMScheduler):
+ latents = self.scheduler.step(noise_pred, t, latents, **extra_step_kwargs, return_dict=False)[0]
+ else:
+ latents, old_pred_original_sample = self.scheduler.step(
+ noise_pred,
+ old_pred_original_sample,
+ t,
+ timesteps[i - 1] if i > 0 else None,
+ latents,
+ **extra_step_kwargs,
+ return_dict=False,
+ )
+ latents = latents.to(prompt_embeds.dtype)
+
+ # call the callback, if provided
+ if callback_on_step_end is not None:
+ callback_kwargs = {}
+ for k in callback_on_step_end_tensor_inputs:
+ callback_kwargs[k] = locals()[k]
+ callback_outputs = callback_on_step_end(self, i, t, callback_kwargs)
+
+ latents = callback_outputs.pop("latents", latents)
+ prompt_embeds = callback_outputs.pop("prompt_embeds", prompt_embeds)
+ negative_prompt_embeds = callback_outputs.pop("negative_prompt_embeds", negative_prompt_embeds)
+
+ if i == len(timesteps) - 1 or ((i + 1) > num_warmup_steps and (i + 1) % self.scheduler.order == 0):
+ progress_bar.update()
+ if comfyui_progressbar:
+ pbar.update(1)
+
+ if output_type == "numpy":
+ video = self.decode_latents(latents)
+ elif not output_type == "latent":
+ video = self.decode_latents(latents)
+ video = self.video_processor.postprocess_video(video=video, output_type=output_type)
+ else:
+ video = latents
+
+ # Offload all models
+ self.maybe_free_model_hooks()
+
+ if not return_dict:
+ video = torch.from_numpy(video)
+
+ return CogVideoX_FUN_PipelineOutput(videos=video)
diff --git a/cogvideox/ui/ui.py b/cogvideox/ui/ui.py
new file mode 100644
index 0000000..f86cdc7
--- /dev/null
+++ b/cogvideox/ui/ui.py
@@ -0,0 +1,1403 @@
+"""Modified from https://github.com/guoyww/AnimateDiff/blob/main/app.py
+"""
+import base64
+import gc
+import json
+import os
+import random
+from datetime import datetime
+from glob import glob
+
+import cv2
+import gradio as gr
+import numpy as np
+import pkg_resources
+import requests
+import torch
+from diffusers import (AutoencoderKL, AutoencoderKLCogVideoX,
+ CogVideoXDDIMScheduler, DDIMScheduler,
+ DPMSolverMultistepScheduler,
+ EulerAncestralDiscreteScheduler, EulerDiscreteScheduler,
+ PNDMScheduler)
+from diffusers.utils.import_utils import is_xformers_available
+from omegaconf import OmegaConf
+from PIL import Image
+from safetensors import safe_open
+from transformers import (CLIPImageProcessor, CLIPVisionModelWithProjection,
+ T5EncoderModel, T5Tokenizer)
+
+from cogvideox.data.bucket_sampler import ASPECT_RATIO_512, get_closest_ratio
+from ..models.autoencoder_magvit import AutoencoderKLCogVideoX
+from cogvideox.models.transformer3d import CogVideoXTransformer3DModel
+from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_FUN_Pipeline
+from cogvideox.pipeline.pipeline_cogvideox_inpaint import \
+ CogVideoX_FUN_Pipeline_Inpaint
+from cogvideox.utils.lora_utils import merge_lora, unmerge_lora
+from cogvideox.utils.utils import (
+ get_image_to_video_latent, get_video_to_video_latent,
+ get_width_and_height_from_image_and_base_resolution, save_videos_grid)
+
+scheduler_dict = {
+ "Euler": EulerDiscreteScheduler,
+ "Euler A": EulerAncestralDiscreteScheduler,
+ "DPM++": DPMSolverMultistepScheduler,
+ "PNDM": PNDMScheduler,
+ "DDIM_Cog": CogVideoXDDIMScheduler,
+ "DDIM_Origin": DDIMScheduler,
+}
+
+gradio_version = pkg_resources.get_distribution("gradio").version
+gradio_version_is_above_4 = True if int(gradio_version.split('.')[0]) >= 4 else False
+
+css = """
+.toolbutton {
+ margin-buttom: 0em 0em 0em 0em;
+ max-width: 2.5em;
+ min-width: 2.5em !important;
+ height: 2.5em;
+}
+"""
+
+class CogVideoX_I2VController:
+ def __init__(self, low_gpu_memory_mode, weight_dtype):
+ # config dirs
+ self.basedir = os.getcwd()
+ self.config_dir = os.path.join(self.basedir, "config")
+ self.diffusion_transformer_dir = os.path.join(self.basedir, "models", "Diffusion_Transformer")
+ self.motion_module_dir = os.path.join(self.basedir, "models", "Motion_Module")
+ self.personalized_model_dir = os.path.join(self.basedir, "models", "Personalized_Model")
+ self.savedir = os.path.join(self.basedir, "samples", datetime.now().strftime("Gradio-%Y-%m-%dT%H-%M-%S"))
+ self.savedir_sample = os.path.join(self.savedir, "sample")
+ os.makedirs(self.savedir, exist_ok=True)
+
+ self.diffusion_transformer_list = []
+ self.motion_module_list = []
+ self.personalized_model_list = []
+
+ self.refresh_diffusion_transformer()
+ self.refresh_motion_module()
+ self.refresh_personalized_model()
+
+ # config models
+ self.tokenizer = None
+ self.text_encoder = None
+ self.vae = None
+ self.transformer = None
+ self.pipeline = None
+ self.motion_module_path = "none"
+ self.base_model_path = "none"
+ self.lora_model_path = "none"
+ self.low_gpu_memory_mode = low_gpu_memory_mode
+
+ self.weight_dtype = weight_dtype
+
+ def refresh_diffusion_transformer(self):
+ self.diffusion_transformer_list = sorted(glob(os.path.join(self.diffusion_transformer_dir, "*/")))
+
+ def refresh_motion_module(self):
+ motion_module_list = sorted(glob(os.path.join(self.motion_module_dir, "*.safetensors")))
+ self.motion_module_list = [os.path.basename(p) for p in motion_module_list]
+
+ def refresh_personalized_model(self):
+ personalized_model_list = sorted(glob(os.path.join(self.personalized_model_dir, "*.safetensors")))
+ self.personalized_model_list = [os.path.basename(p) for p in personalized_model_list]
+
+ def update_diffusion_transformer(self, diffusion_transformer_dropdown):
+ print("Update diffusion transformer")
+ if diffusion_transformer_dropdown == "none":
+ return gr.update()
+ self.vae = AutoencoderKLCogVideoX.from_pretrained(
+ diffusion_transformer_dropdown,
+ subfolder="vae",
+ ).to(self.weight_dtype)
+
+ # Get Transformer
+ self.transformer = CogVideoXTransformer3DModel.from_pretrained_2d(
+ diffusion_transformer_dropdown,
+ subfolder="transformer",
+ ).to(self.weight_dtype)
+
+ # Get pipeline
+ if self.transformer.config.in_channels != self.vae.config.latent_channels:
+ self.pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
+ diffusion_transformer_dropdown,
+ vae=self.vae,
+ transformer=self.transformer,
+ scheduler=scheduler_dict["Euler"].from_pretrained(diffusion_transformer_dropdown, subfolder="scheduler"),
+ torch_dtype=self.weight_dtype
+ )
+ else:
+ self.pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
+ diffusion_transformer_dropdown,
+ vae=self.vae,
+ transformer=self.transformer,
+ scheduler=scheduler_dict["Euler"].from_pretrained(diffusion_transformer_dropdown, subfolder="scheduler"),
+ torch_dtype=self.weight_dtype
+ )
+
+ if self.low_gpu_memory_mode:
+ self.pipeline.enable_sequential_cpu_offload()
+ else:
+ self.pipeline.enable_model_cpu_offload()
+ print("Update diffusion transformer done")
+ return gr.update()
+
+ def update_base_model(self, base_model_dropdown):
+ self.base_model_path = base_model_dropdown
+ print("Update base model")
+ if base_model_dropdown == "none":
+ return gr.update()
+ if self.transformer is None:
+ gr.Info(f"Please select a pretrained model path.")
+ return gr.update(value=None)
+ else:
+ base_model_dropdown = os.path.join(self.personalized_model_dir, base_model_dropdown)
+ base_model_state_dict = {}
+ with safe_open(base_model_dropdown, framework="pt", device="cpu") as f:
+ for key in f.keys():
+ base_model_state_dict[key] = f.get_tensor(key)
+ self.transformer.load_state_dict(base_model_state_dict, strict=False)
+ print("Update base done")
+ return gr.update()
+
+ def update_lora_model(self, lora_model_dropdown):
+ print("Update lora model")
+ if lora_model_dropdown == "none":
+ self.lora_model_path = "none"
+ return gr.update()
+ lora_model_dropdown = os.path.join(self.personalized_model_dir, lora_model_dropdown)
+ self.lora_model_path = lora_model_dropdown
+ return gr.update()
+
+ def generate(
+ self,
+ diffusion_transformer_dropdown,
+ base_model_dropdown,
+ lora_model_dropdown,
+ lora_alpha_slider,
+ prompt_textbox,
+ negative_prompt_textbox,
+ sampler_dropdown,
+ sample_step_slider,
+ resize_method,
+ width_slider,
+ height_slider,
+ base_resolution,
+ generation_method,
+ length_slider,
+ overlap_video_length,
+ partial_video_length,
+ cfg_scale_slider,
+ start_image,
+ end_image,
+ validation_video,
+ denoise_strength,
+ seed_textbox,
+ is_api = False,
+ ):
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.ipc_collect()
+
+ if self.transformer is None:
+ raise gr.Error(f"Please select a pretrained model path.")
+
+ if self.base_model_path != base_model_dropdown:
+ self.update_base_model(base_model_dropdown)
+
+ if self.lora_model_path != lora_model_dropdown:
+ print("Update lora model")
+ self.update_lora_model(lora_model_dropdown)
+
+ if resize_method == "Resize according to Reference":
+ if start_image is None and validation_video is None:
+ if is_api:
+ return "", f"Please upload an image when using \"Resize according to Reference\"."
+ else:
+ raise gr.Error(f"Please upload an image when using \"Resize according to Reference\".")
+
+ aspect_ratio_sample_size = {key : [x / 512 * base_resolution for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+
+ if validation_video is not None:
+ original_width, original_height = Image.fromarray(cv2.VideoCapture(validation_video).read()[1]).size
+ else:
+ original_width, original_height = start_image[0].size if type(start_image) is list else Image.open(start_image).size
+ closest_size, closest_ratio = get_closest_ratio(original_height, original_width, ratios=aspect_ratio_sample_size)
+ height_slider, width_slider = [int(x / 16) * 16 for x in closest_size]
+
+ if self.transformer.config.in_channels == self.vae.config.latent_channels and start_image is not None:
+ if is_api:
+ return "", f"Please select an image to video pretrained model while using image to video."
+ else:
+ raise gr.Error(f"Please select an image to video pretrained model while using image to video.")
+
+ if self.transformer.config.in_channels == self.vae.config.latent_channels and generation_method == "Long Video Generation":
+ if is_api:
+ return "", f"Please select an image to video pretrained model while using long video generation."
+ else:
+ raise gr.Error(f"Please select an image to video pretrained model while using long video generation.")
+
+ if start_image is None and end_image is not None:
+ if is_api:
+ return "", f"If specifying the ending image of the video, please specify a starting image of the video."
+ else:
+ raise gr.Error(f"If specifying the ending image of the video, please specify a starting image of the video.")
+
+ is_image = True if generation_method == "Image Generation" else False
+
+ self.pipeline.scheduler = scheduler_dict[sampler_dropdown].from_config(self.pipeline.scheduler.config)
+ if self.lora_model_path != "none":
+ # lora part
+ self.pipeline = merge_lora(self.pipeline, self.lora_model_path, multiplier=lora_alpha_slider)
+
+ if int(seed_textbox) != -1 and seed_textbox != "": torch.manual_seed(int(seed_textbox))
+ else: seed_textbox = np.random.randint(0, 1e10)
+ generator = torch.Generator(device="cuda").manual_seed(int(seed_textbox))
+
+ try:
+ if self.transformer.config.in_channels != self.vae.config.latent_channels:
+ if generation_method == "Long Video Generation":
+ if validation_video is not None:
+ raise gr.Error(f"Video to Video is not Support Long Video Generation now.")
+ init_frames = 0
+ last_frames = init_frames + partial_video_length
+ while init_frames < length_slider:
+ if last_frames >= length_slider:
+ _partial_video_length = length_slider - init_frames
+ _partial_video_length = int((_partial_video_length - 1) // self.vae.config.temporal_compression_ratio * self.vae.config.temporal_compression_ratio) + 1
+
+ if _partial_video_length <= 0:
+ break
+ else:
+ _partial_video_length = partial_video_length
+
+ if last_frames >= length_slider:
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(start_image, end_image, video_length=_partial_video_length, sample_size=(height_slider, width_slider))
+ else:
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(start_image, None, video_length=_partial_video_length, sample_size=(height_slider, width_slider))
+
+ with torch.no_grad():
+ sample = self.pipeline(
+ prompt_textbox,
+ negative_prompt = negative_prompt_textbox,
+ num_inference_steps = sample_step_slider,
+ guidance_scale = cfg_scale_slider,
+ width = width_slider,
+ height = height_slider,
+ num_frames = _partial_video_length,
+ generator = generator,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ strength = 1,
+ ).videos
+
+ if init_frames != 0:
+ mix_ratio = torch.from_numpy(
+ np.array([float(_index) / float(overlap_video_length) for _index in range(overlap_video_length)], np.float32)
+ ).unsqueeze(0).unsqueeze(0).unsqueeze(-1).unsqueeze(-1)
+
+ new_sample[:, :, -overlap_video_length:] = new_sample[:, :, -overlap_video_length:] * (1 - mix_ratio) + \
+ sample[:, :, :overlap_video_length] * mix_ratio
+ new_sample = torch.cat([new_sample, sample[:, :, overlap_video_length:]], dim = 2)
+
+ sample = new_sample
+ else:
+ new_sample = sample
+
+ if last_frames >= length_slider:
+ break
+
+ start_image = [
+ Image.fromarray(
+ (sample[0, :, _index].transpose(0, 1).transpose(1, 2) * 255).numpy().astype(np.uint8)
+ ) for _index in range(-overlap_video_length, 0)
+ ]
+
+ init_frames = init_frames + _partial_video_length - overlap_video_length
+ last_frames = init_frames + _partial_video_length
+ else:
+ if validation_video is not None:
+ input_video, input_video_mask, clip_image = get_video_to_video_latent(validation_video, length_slider if not is_image else 1, sample_size=(height_slider, width_slider))
+ strength = denoise_strength
+ else:
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(start_image, end_image, length_slider if not is_image else 1, sample_size=(height_slider, width_slider))
+ strength = 1
+
+ sample = self.pipeline(
+ prompt_textbox,
+ negative_prompt = negative_prompt_textbox,
+ num_inference_steps = sample_step_slider,
+ guidance_scale = cfg_scale_slider,
+ width = width_slider,
+ height = height_slider,
+ num_frames = length_slider if not is_image else 1,
+ generator = generator,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ strength = strength,
+ ).videos
+ else:
+ sample = self.pipeline(
+ prompt_textbox,
+ negative_prompt = negative_prompt_textbox,
+ num_inference_steps = sample_step_slider,
+ guidance_scale = cfg_scale_slider,
+ width = width_slider,
+ height = height_slider,
+ num_frames = length_slider if not is_image else 1,
+ generator = generator
+ ).videos
+ except Exception as e:
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.ipc_collect()
+ if self.lora_model_path != "none":
+ self.pipeline = unmerge_lora(self.pipeline, self.lora_model_path, multiplier=lora_alpha_slider)
+ if is_api:
+ return "", f"Error. error information is {str(e)}"
+ else:
+ return gr.update(), gr.update(), f"Error. error information is {str(e)}"
+
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.ipc_collect()
+
+ # lora part
+ if self.lora_model_path != "none":
+ self.pipeline = unmerge_lora(self.pipeline, self.lora_model_path, multiplier=lora_alpha_slider)
+
+ sample_config = {
+ "prompt": prompt_textbox,
+ "n_prompt": negative_prompt_textbox,
+ "sampler": sampler_dropdown,
+ "num_inference_steps": sample_step_slider,
+ "guidance_scale": cfg_scale_slider,
+ "width": width_slider,
+ "height": height_slider,
+ "video_length": length_slider,
+ "seed_textbox": seed_textbox
+ }
+ json_str = json.dumps(sample_config, indent=4)
+ with open(os.path.join(self.savedir, "logs.json"), "a") as f:
+ f.write(json_str)
+ f.write("\n\n")
+
+ if not os.path.exists(self.savedir_sample):
+ os.makedirs(self.savedir_sample, exist_ok=True)
+ index = len([path for path in os.listdir(self.savedir_sample)]) + 1
+ prefix = str(index).zfill(3)
+
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.ipc_collect()
+ if is_image or length_slider == 1:
+ save_sample_path = os.path.join(self.savedir_sample, prefix + f".png")
+
+ image = sample[0, :, 0]
+ image = image.transpose(0, 1).transpose(1, 2)
+ image = (image * 255).numpy().astype(np.uint8)
+ image = Image.fromarray(image)
+ image.save(save_sample_path)
+
+ if is_api:
+ return save_sample_path, "Success"
+ else:
+ if gradio_version_is_above_4:
+ return gr.Image(value=save_sample_path, visible=True), gr.Video(value=None, visible=False), "Success"
+ else:
+ return gr.Image.update(value=save_sample_path, visible=True), gr.Video.update(value=None, visible=False), "Success"
+ else:
+ save_sample_path = os.path.join(self.savedir_sample, prefix + f".mp4")
+ save_videos_grid(sample, save_sample_path, fps=8)
+
+ if is_api:
+ return save_sample_path, "Success"
+ else:
+ if gradio_version_is_above_4:
+ return gr.Image(visible=False, value=None), gr.Video(value=save_sample_path, visible=True), "Success"
+ else:
+ return gr.Image.update(visible=False, value=None), gr.Video.update(value=save_sample_path, visible=True), "Success"
+
+
+def ui(low_gpu_memory_mode, weight_dtype):
+ controller = CogVideoX_I2VController(low_gpu_memory_mode, weight_dtype)
+
+ with gr.Blocks(css=css) as demo:
+ gr.Markdown(
+ """
+ # CogVideoX-Arbitrary:
+
+ A CogVideoX with more flexible generation conditions, capable of producing videos of different resolutions, around 6 seconds, and fps 8 (frames 1 to 49), as well as image generated videos.
+
+ [Github](https://github.com/aigc-apps/CogVideoX-Arbitrary/)
+ """
+ )
+ with gr.Column(variant="panel"):
+ gr.Markdown(
+ """
+ ### 1. Model checkpoints (模型路径).
+ """
+ )
+ with gr.Row():
+ diffusion_transformer_dropdown = gr.Dropdown(
+ label="Pretrained Model Path (预训练模型路径)",
+ choices=controller.diffusion_transformer_list,
+ value="none",
+ interactive=True,
+ )
+ diffusion_transformer_dropdown.change(
+ fn=controller.update_diffusion_transformer,
+ inputs=[diffusion_transformer_dropdown],
+ outputs=[diffusion_transformer_dropdown]
+ )
+
+ diffusion_transformer_refresh_button = gr.Button(value="\U0001F503", elem_classes="toolbutton")
+ def refresh_diffusion_transformer():
+ controller.refresh_diffusion_transformer()
+ return gr.update(choices=controller.diffusion_transformer_list)
+ diffusion_transformer_refresh_button.click(fn=refresh_diffusion_transformer, inputs=[], outputs=[diffusion_transformer_dropdown])
+
+ with gr.Row():
+ base_model_dropdown = gr.Dropdown(
+ label="Select base Dreambooth model (选择基模型[非必需])",
+ choices=controller.personalized_model_list,
+ value="none",
+ interactive=True,
+ )
+
+ lora_model_dropdown = gr.Dropdown(
+ label="Select LoRA model (选择LoRA模型[非必需])",
+ choices=["none"] + controller.personalized_model_list,
+ value="none",
+ interactive=True,
+ )
+
+ lora_alpha_slider = gr.Slider(label="LoRA alpha (LoRA权重)", value=0.55, minimum=0, maximum=2, interactive=True)
+
+ personalized_refresh_button = gr.Button(value="\U0001F503", elem_classes="toolbutton")
+ def update_personalized_model():
+ controller.refresh_personalized_model()
+ return [
+ gr.update(choices=controller.personalized_model_list),
+ gr.update(choices=["none"] + controller.personalized_model_list)
+ ]
+ personalized_refresh_button.click(fn=update_personalized_model, inputs=[], outputs=[base_model_dropdown, lora_model_dropdown])
+
+ with gr.Column(variant="panel"):
+ gr.Markdown(
+ """
+ ### 2. Configs for Generation (生成参数配置).
+ """
+ )
+
+ prompt_textbox = gr.Textbox(label="Prompt (正向提示词)", lines=2, value="A young woman with beautiful and clear eyes and blonde hair standing and white dress in a forest wearing a crown. She seems to be lost in thought, and the camera focuses on her face. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.")
+ negative_prompt_textbox = gr.Textbox(label="Negative prompt (负向提示词)", lines=2, value="The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion." )
+
+ with gr.Row():
+ with gr.Column():
+ with gr.Row():
+ sampler_dropdown = gr.Dropdown(label="Sampling method (采样器种类)", choices=list(scheduler_dict.keys()), value=list(scheduler_dict.keys())[0])
+ sample_step_slider = gr.Slider(label="Sampling steps (生成步数)", value=30, minimum=10, maximum=100, step=1)
+
+ resize_method = gr.Radio(
+ ["Generate by", "Resize according to Reference"],
+ value="Generate by",
+ show_label=False,
+ )
+ width_slider = gr.Slider(label="Width (视频宽度)", value=672, minimum=128, maximum=1344, step=16)
+ height_slider = gr.Slider(label="Height (视频高度)", value=384, minimum=128, maximum=1344, step=16)
+ base_resolution = gr.Radio(label="Base Resolution of Pretrained Models", value=512, choices=[512, 768, 960], visible=False)
+
+ with gr.Group():
+ generation_method = gr.Radio(
+ ["Video Generation", "Image Generation", "Long Video Generation"],
+ value="Video Generation",
+ show_label=False,
+ )
+ with gr.Row():
+ length_slider = gr.Slider(label="Animation length (视频帧数)", value=49, minimum=1, maximum=49, step=4)
+ overlap_video_length = gr.Slider(label="Overlap length (视频续写的重叠帧数)", value=4, minimum=1, maximum=4, step=1, visible=False)
+ partial_video_length = gr.Slider(label="Partial video generation length (每个部分的视频生成帧数)", value=25, minimum=5, maximum=49, step=4, visible=False)
+
+ source_method = gr.Radio(
+ ["Text to Video (文本到视频)", "Image to Video (图片到视频)", "Video to Video (视频到视频)"],
+ value="Text to Video (文本到视频)",
+ show_label=False,
+ )
+ with gr.Column(visible = False) as image_to_video_col:
+ start_image = gr.Image(
+ label="The image at the beginning of the video (图片到视频的开始图片)", show_label=True,
+ elem_id="i2v_start", sources="upload", type="filepath",
+ )
+
+ template_gallery_path = ["asset/1.png", "asset/2.png", "asset/3.png", "asset/4.png", "asset/5.png"]
+ def select_template(evt: gr.SelectData):
+ text = {
+ "asset/1.png": "The dog is looking at camera and smiling. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ "asset/2.png": "a sailboat sailing in rough seas with a dramatic sunset. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ "asset/3.png": "a beautiful woman with long hair and a dress blowing in the wind. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ "asset/4.png": "a man in an astronaut suit playing a guitar. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ "asset/5.png": "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ }[template_gallery_path[evt.index]]
+ return template_gallery_path[evt.index], text
+
+ template_gallery = gr.Gallery(
+ template_gallery_path,
+ columns=5, rows=1,
+ height=140,
+ allow_preview=False,
+ container=False,
+ label="Template Examples",
+ )
+ template_gallery.select(select_template, None, [start_image, prompt_textbox])
+
+ with gr.Accordion("The image at the ending of the video (图片到视频的结束图片[非必需, Optional])", open=False):
+ end_image = gr.Image(label="The image at the ending of the video (图片到视频的结束图片[非必需, Optional])", show_label=False, elem_id="i2v_end", sources="upload", type="filepath")
+
+ with gr.Column(visible = False) as video_to_video_col:
+ validation_video = gr.Video(
+ label="The video to convert (视频转视频的参考视频)", show_label=True,
+ elem_id="v2v", sources="upload",
+ )
+ denoise_strength = gr.Slider(label="Denoise strength (重绘系数)", value=0.70, minimum=0.10, maximum=0.95, step=0.01)
+
+ cfg_scale_slider = gr.Slider(label="CFG Scale (引导系数)", value=7.0, minimum=0, maximum=20)
+
+ with gr.Row():
+ seed_textbox = gr.Textbox(label="Seed (随机种子)", value=43)
+ seed_button = gr.Button(value="\U0001F3B2", elem_classes="toolbutton")
+ seed_button.click(
+ fn=lambda: gr.Textbox(value=random.randint(1, 1e8)) if gradio_version_is_above_4 else gr.Textbox.update(value=random.randint(1, 1e8)),
+ inputs=[],
+ outputs=[seed_textbox]
+ )
+
+ generate_button = gr.Button(value="Generate (生成)", variant='primary')
+
+ with gr.Column():
+ result_image = gr.Image(label="Generated Image (生成图片)", interactive=False, visible=False)
+ result_video = gr.Video(label="Generated Animation (生成视频)", interactive=False)
+ infer_progress = gr.Textbox(
+ label="Generation Info (生成信息)",
+ value="No task currently",
+ interactive=False
+ )
+
+ def upload_generation_method(generation_method):
+ if generation_method == "Video Generation":
+ return [gr.update(visible=True, maximum=49, value=49), gr.update(visible=False), gr.update(visible=False)]
+ elif generation_method == "Image Generation":
+ return [gr.update(visible=False), gr.update(visible=False), gr.update(visible=False)]
+ else:
+ return [gr.update(visible=True, maximum=1344), gr.update(visible=True), gr.update(visible=True)]
+ generation_method.change(
+ upload_generation_method, generation_method, [length_slider, overlap_video_length, partial_video_length]
+ )
+
+ def upload_source_method(source_method):
+ if source_method == "Text to Video (文本到视频)":
+ return [gr.update(visible=False), gr.update(visible=False), gr.update(value=None), gr.update(value=None), gr.update(value=None)]
+ elif source_method == "Image to Video (图片到视频)":
+ return [gr.update(visible=True), gr.update(visible=False), gr.update(), gr.update(), gr.update(value=None)]
+ else:
+ return [gr.update(visible=False), gr.update(visible=True), gr.update(value=None), gr.update(value=None), gr.update()]
+ source_method.change(
+ upload_source_method, source_method, [image_to_video_col, video_to_video_col, start_image, end_image, validation_video]
+ )
+
+ def upload_resize_method(resize_method):
+ if resize_method == "Generate by":
+ return [gr.update(visible=True), gr.update(visible=True), gr.update(visible=False)]
+ else:
+ return [gr.update(visible=False), gr.update(visible=False), gr.update(visible=True)]
+ resize_method.change(
+ upload_resize_method, resize_method, [width_slider, height_slider, base_resolution]
+ )
+
+ generate_button.click(
+ fn=controller.generate,
+ inputs=[
+ diffusion_transformer_dropdown,
+ base_model_dropdown,
+ lora_model_dropdown,
+ lora_alpha_slider,
+ prompt_textbox,
+ negative_prompt_textbox,
+ sampler_dropdown,
+ sample_step_slider,
+ resize_method,
+ width_slider,
+ height_slider,
+ base_resolution,
+ generation_method,
+ length_slider,
+ overlap_video_length,
+ partial_video_length,
+ cfg_scale_slider,
+ start_image,
+ end_image,
+ validation_video,
+ denoise_strength,
+ seed_textbox,
+ ],
+ outputs=[result_image, result_video, infer_progress]
+ )
+ return demo, controller
+
+
+class CogVideoX_I2VController_Modelscope:
+ def __init__(self, model_name, savedir_sample, low_gpu_memory_mode, weight_dtype):
+ # Basic dir
+ self.basedir = os.getcwd()
+ self.personalized_model_dir = os.path.join(self.basedir, "models", "Personalized_Model")
+ self.lora_model_path = "none"
+ self.savedir_sample = savedir_sample
+ self.refresh_personalized_model()
+ os.makedirs(self.savedir_sample, exist_ok=True)
+
+ # model path
+ self.weight_dtype = weight_dtype
+
+ self.vae = AutoencoderKLCogVideoX.from_pretrained(
+ model_name,
+ subfolder="vae",
+ ).to(self.weight_dtype)
+
+ # Get Transformer
+ self.transformer = CogVideoXTransformer3DModel.from_pretrained_2d(
+ model_name,
+ subfolder="transformer",
+ ).to(self.weight_dtype)
+
+ # Get pipeline
+ if self.transformer.config.in_channels != self.vae.config.latent_channels:
+ self.pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
+ model_name,
+ vae=self.vae,
+ transformer=self.transformer,
+ scheduler=scheduler_dict["Euler"].from_pretrained(model_name, subfolder="scheduler"),
+ torch_dtype=self.weight_dtype
+ )
+ else:
+ self.pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
+ model_name,
+ vae=self.vae,
+ transformer=self.transformer,
+ scheduler=scheduler_dict["Euler"].from_pretrained(model_name, subfolder="scheduler"),
+ torch_dtype=self.weight_dtype
+ )
+
+ if low_gpu_memory_mode:
+ self.pipeline.enable_sequential_cpu_offload()
+ else:
+ self.pipeline.enable_model_cpu_offload()
+ print("Update diffusion transformer done")
+
+
+ def refresh_personalized_model(self):
+ personalized_model_list = sorted(glob(os.path.join(self.personalized_model_dir, "*.safetensors")))
+ self.personalized_model_list = [os.path.basename(p) for p in personalized_model_list]
+
+
+ def update_lora_model(self, lora_model_dropdown):
+ print("Update lora model")
+ if lora_model_dropdown == "none":
+ self.lora_model_path = "none"
+ return gr.update()
+ lora_model_dropdown = os.path.join(self.personalized_model_dir, lora_model_dropdown)
+ self.lora_model_path = lora_model_dropdown
+ return gr.update()
+
+
+ def generate(
+ self,
+ diffusion_transformer_dropdown,
+ base_model_dropdown,
+ lora_model_dropdown,
+ lora_alpha_slider,
+ prompt_textbox,
+ negative_prompt_textbox,
+ sampler_dropdown,
+ sample_step_slider,
+ resize_method,
+ width_slider,
+ height_slider,
+ base_resolution,
+ generation_method,
+ length_slider,
+ overlap_video_length,
+ partial_video_length,
+ cfg_scale_slider,
+ start_image,
+ end_image,
+ validation_video,
+ denoise_strength,
+ seed_textbox,
+ is_api = False,
+ ):
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.ipc_collect()
+
+ if self.transformer is None:
+ raise gr.Error(f"Please select a pretrained model path.")
+
+ if self.lora_model_path != lora_model_dropdown:
+ print("Update lora model")
+ self.update_lora_model(lora_model_dropdown)
+
+ if resize_method == "Resize according to Reference":
+ if start_image is None and validation_video is None:
+ raise gr.Error(f"Please upload an image when using \"Resize according to Reference\".")
+
+ aspect_ratio_sample_size = {key : [x / 512 * base_resolution for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+
+ if validation_video is not None:
+ original_width, original_height = Image.fromarray(cv2.VideoCapture(validation_video).read()[1]).size
+ else:
+ original_width, original_height = start_image[0].size if type(start_image) is list else Image.open(start_image).size
+ closest_size, closest_ratio = get_closest_ratio(original_height, original_width, ratios=aspect_ratio_sample_size)
+ height_slider, width_slider = [int(x / 16) * 16 for x in closest_size]
+
+ if self.transformer.config.in_channels == self.vae.config.latent_channels and start_image is not None:
+ raise gr.Error(f"Please select an image to video pretrained model while using image to video.")
+
+ if start_image is None and end_image is not None:
+ raise gr.Error(f"If specifying the ending image of the video, please specify a starting image of the video.")
+
+ is_image = True if generation_method == "Image Generation" else False
+
+ self.pipeline.scheduler = scheduler_dict[sampler_dropdown].from_config(self.pipeline.scheduler.config)
+ if self.lora_model_path != "none":
+ # lora part
+ self.pipeline = merge_lora(self.pipeline, self.lora_model_path, multiplier=lora_alpha_slider)
+
+ if int(seed_textbox) != -1 and seed_textbox != "": torch.manual_seed(int(seed_textbox))
+ else: seed_textbox = np.random.randint(0, 1e10)
+ generator = torch.Generator(device="cuda").manual_seed(int(seed_textbox))
+
+ try:
+ if self.transformer.config.in_channels != self.vae.config.latent_channels:
+ if validation_video is not None:
+ input_video, input_video_mask, clip_image = get_video_to_video_latent(validation_video, length_slider if not is_image else 1, sample_size=(height_slider, width_slider))
+ strength = denoise_strength
+ else:
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(start_image, end_image, length_slider if not is_image else 1, sample_size=(height_slider, width_slider))
+ strength = 1
+
+ sample = self.pipeline(
+ prompt_textbox,
+ negative_prompt = negative_prompt_textbox,
+ num_inference_steps = sample_step_slider,
+ guidance_scale = cfg_scale_slider,
+ width = width_slider,
+ height = height_slider,
+ num_frames = length_slider if not is_image else 1,
+ generator = generator,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ strength = strength,
+ ).videos
+ else:
+ sample = self.pipeline(
+ prompt_textbox,
+ negative_prompt = negative_prompt_textbox,
+ num_inference_steps = sample_step_slider,
+ guidance_scale = cfg_scale_slider,
+ width = width_slider,
+ height = height_slider,
+ num_frames = length_slider if not is_image else 1,
+ generator = generator
+ ).videos
+ except Exception as e:
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.ipc_collect()
+ if self.lora_model_path != "none":
+ self.pipeline = unmerge_lora(self.pipeline, self.lora_model_path, multiplier=lora_alpha_slider)
+ if is_api:
+ return "", f"Error. error information is {str(e)}"
+ else:
+ return gr.update(), gr.update(), f"Error. error information is {str(e)}"
+
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.ipc_collect()
+
+ # lora part
+ if self.lora_model_path != "none":
+ self.pipeline = unmerge_lora(self.pipeline, self.lora_model_path, multiplier=lora_alpha_slider)
+
+ if not os.path.exists(self.savedir_sample):
+ os.makedirs(self.savedir_sample, exist_ok=True)
+ index = len([path for path in os.listdir(self.savedir_sample)]) + 1
+ prefix = str(index).zfill(3)
+
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.ipc_collect()
+ if is_image or length_slider == 1:
+ save_sample_path = os.path.join(self.savedir_sample, prefix + f".png")
+
+ image = sample[0, :, 0]
+ image = image.transpose(0, 1).transpose(1, 2)
+ image = (image * 255).numpy().astype(np.uint8)
+ image = Image.fromarray(image)
+ image.save(save_sample_path)
+ if is_api:
+ return save_sample_path, "Success"
+ else:
+ if gradio_version_is_above_4:
+ return gr.Image(value=save_sample_path, visible=True), gr.Video(value=None, visible=False), "Success"
+ else:
+ return gr.Image.update(value=save_sample_path, visible=True), gr.Video.update(value=None, visible=False), "Success"
+ else:
+ save_sample_path = os.path.join(self.savedir_sample, prefix + f".mp4")
+ save_videos_grid(sample, save_sample_path, fps=8)
+ if is_api:
+ return save_sample_path, "Success"
+ else:
+ if gradio_version_is_above_4:
+ return gr.Image(visible=False, value=None), gr.Video(value=save_sample_path, visible=True), "Success"
+ else:
+ return gr.Image.update(visible=False, value=None), gr.Video.update(value=save_sample_path, visible=True), "Success"
+
+
+def ui_modelscope(model_name, savedir_sample, low_gpu_memory_mode, weight_dtype):
+ controller = CogVideoX_I2VController_Modelscope(model_name, savedir_sample, low_gpu_memory_mode, weight_dtype)
+
+ with gr.Blocks(css=css) as demo:
+ gr.Markdown(
+ """
+ # CogVideoX-Arbitrary
+
+ A CogVideoX with more flexible generation conditions, capable of producing videos of different resolutions, around 6 seconds, and fps 8 (frames 1 to 49), as well as image generated videos.
+
+ [Github](https://github.com/aigc-apps/CogVideoX-Arbitrary/)
+ """
+ )
+ with gr.Column(variant="panel"):
+ gr.Markdown(
+ """
+ ### 1. Model checkpoints (模型路径).
+ """
+ )
+ with gr.Row():
+ diffusion_transformer_dropdown = gr.Dropdown(
+ label="Pretrained Model Path (预训练模型路径)",
+ choices=[model_name],
+ value=model_name,
+ interactive=False,
+ )
+ with gr.Row():
+ base_model_dropdown = gr.Dropdown(
+ label="Select base Dreambooth model (选择基模型[非必需])",
+ choices=["none"],
+ value="none",
+ interactive=False,
+ visible=False
+ )
+ with gr.Column(visible=False):
+ gr.Markdown(
+ """
+ ### Minimalism is an example portrait of Lora, triggered by specific prompt words. More details can be found on [Wiki](https://github.com/aigc-apps/CogVideoX-Arbitrary/wiki/Training-Lora).
+ """
+ )
+ with gr.Row():
+ lora_model_dropdown = gr.Dropdown(
+ label="Select LoRA model",
+ choices=["none"],
+ value="none",
+ interactive=True,
+ )
+
+ lora_alpha_slider = gr.Slider(label="LoRA alpha (LoRA权重)", value=0.55, minimum=0, maximum=2, interactive=True)
+
+ with gr.Column(variant="panel"):
+ gr.Markdown(
+ """
+ ### 2. Configs for Generation (生成参数配置).
+ """
+ )
+
+ prompt_textbox = gr.Textbox(label="Prompt (正向提示词)", lines=2, value="A young woman with beautiful and clear eyes and blonde hair standing and white dress in a forest wearing a crown. She seems to be lost in thought, and the camera focuses on her face. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.")
+ negative_prompt_textbox = gr.Textbox(label="Negative prompt (负向提示词)", lines=2, value="The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion." )
+
+ with gr.Row():
+ with gr.Column():
+ with gr.Row():
+ sampler_dropdown = gr.Dropdown(label="Sampling method (采样器种类)", choices=list(scheduler_dict.keys()), value=list(scheduler_dict.keys())[0])
+ sample_step_slider = gr.Slider(label="Sampling steps (生成步数)", value=20, minimum=10, maximum=30, step=1, interactive=False)
+
+ resize_method = gr.Radio(
+ ["Generate by", "Resize according to Reference"],
+ value="Generate by",
+ show_label=False,
+ )
+ width_slider = gr.Slider(label="Width (视频宽度)", value=672, minimum=128, maximum=1280, step=16, interactive=False)
+ height_slider = gr.Slider(label="Height (视频高度)", value=384, minimum=128, maximum=1280, step=16, interactive=False)
+ base_resolution = gr.Radio(label="Base Resolution of Pretrained Models", value=512, choices=[512, 768, 960], interactive=False, visible=False)
+
+ with gr.Group():
+ generation_method = gr.Radio(
+ ["Video Generation", "Image Generation"],
+ value="Video Generation",
+ show_label=False,
+ visible=True,
+ )
+ length_slider = gr.Slider(label="Animation length (视频帧数)", value=49, minimum=5, maximum=49, step=4)
+ overlap_video_length = gr.Slider(label="Overlap length (视频续写的重叠帧数)", value=4, minimum=1, maximum=4, step=1, visible=False)
+ partial_video_length = gr.Slider(label="Partial video generation length (每个部分的视频生成帧数)", value=25, minimum=5, maximum=49, step=4, visible=False)
+
+ source_method = gr.Radio(
+ ["Text to Video (文本到视频)", "Image to Video (图片到视频)", "Video to Video (视频到视频)"],
+ value="Text to Video (文本到视频)",
+ show_label=False,
+ )
+ with gr.Column(visible = False) as image_to_video_col:
+ with gr.Row():
+ start_image = gr.Image(label="The image at the beginning of the video (图片到视频的开始图片)", show_label=True, elem_id="i2v_start", sources="upload", type="filepath")
+
+ template_gallery_path = ["asset/1.png", "asset/2.png", "asset/3.png", "asset/4.png", "asset/5.png"]
+ def select_template(evt: gr.SelectData):
+ text = {
+ "asset/1.png": "The dog is looking at camera and smiling. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ "asset/2.png": "a sailboat sailing in rough seas with a dramatic sunset. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ "asset/3.png": "a beautiful woman with long hair and a dress blowing in the wind. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ "asset/4.png": "a man in an astronaut suit playing a guitar. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ "asset/5.png": "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ }[template_gallery_path[evt.index]]
+ return template_gallery_path[evt.index], text
+
+ template_gallery = gr.Gallery(
+ template_gallery_path,
+ columns=5, rows=1,
+ height=140,
+ allow_preview=False,
+ container=False,
+ label="Template Examples",
+ )
+ template_gallery.select(select_template, None, [start_image, prompt_textbox])
+
+ with gr.Accordion("The image at the ending of the video (图片到视频的结束图片[非必需, Optional])", open=False):
+ end_image = gr.Image(label="The image at the ending of the video (图片到视频的结束图片[非必需, Optional])", show_label=False, elem_id="i2v_end", sources="upload", type="filepath")
+
+ with gr.Column(visible = False) as video_to_video_col:
+ validation_video = gr.Video(
+ label="The video to convert (视频转视频的参考视频)", show_label=True,
+ elem_id="v2v", sources="upload",
+ )
+ denoise_strength = gr.Slider(label="Denoise strength (重绘系数)", value=0.70, minimum=0.10, maximum=0.95, step=0.01)
+
+ cfg_scale_slider = gr.Slider(label="CFG Scale (引导系数)", value=7.0, minimum=0, maximum=20)
+
+ with gr.Row():
+ seed_textbox = gr.Textbox(label="Seed (随机种子)", value=43)
+ seed_button = gr.Button(value="\U0001F3B2", elem_classes="toolbutton")
+ seed_button.click(
+ fn=lambda: gr.Textbox(value=random.randint(1, 1e8)) if gradio_version_is_above_4 else gr.Textbox.update(value=random.randint(1, 1e8)),
+ inputs=[],
+ outputs=[seed_textbox]
+ )
+
+ generate_button = gr.Button(value="Generate (生成)", variant='primary')
+
+ with gr.Column():
+ result_image = gr.Image(label="Generated Image (生成图片)", interactive=False, visible=False)
+ result_video = gr.Video(label="Generated Animation (生成视频)", interactive=False)
+ infer_progress = gr.Textbox(
+ label="Generation Info (生成信息)",
+ value="No task currently",
+ interactive=False
+ )
+
+ def upload_generation_method(generation_method):
+ if generation_method == "Video Generation":
+ return gr.update(visible=True, minimum=8, maximum=49, value=49, interactive=True)
+ elif generation_method == "Image Generation":
+ return gr.update(minimum=1, maximum=1, value=1, interactive=False)
+ generation_method.change(
+ upload_generation_method, generation_method, [length_slider]
+ )
+
+ def upload_source_method(source_method):
+ if source_method == "Text to Video (文本到视频)":
+ return [gr.update(visible=False), gr.update(visible=False), gr.update(value=None), gr.update(value=None), gr.update(value=None)]
+ elif source_method == "Image to Video (图片到视频)":
+ return [gr.update(visible=True), gr.update(visible=False), gr.update(), gr.update(), gr.update(value=None)]
+ else:
+ return [gr.update(visible=False), gr.update(visible=True), gr.update(value=None), gr.update(value=None), gr.update()]
+ source_method.change(
+ upload_source_method, source_method, [image_to_video_col, video_to_video_col, start_image, end_image, validation_video]
+ )
+
+ def upload_resize_method(resize_method):
+ if resize_method == "Generate by":
+ return [gr.update(visible=True), gr.update(visible=True), gr.update(visible=False)]
+ else:
+ return [gr.update(visible=False), gr.update(visible=False), gr.update(visible=True)]
+ resize_method.change(
+ upload_resize_method, resize_method, [width_slider, height_slider, base_resolution]
+ )
+
+ generate_button.click(
+ fn=controller.generate,
+ inputs=[
+ diffusion_transformer_dropdown,
+ base_model_dropdown,
+ lora_model_dropdown,
+ lora_alpha_slider,
+ prompt_textbox,
+ negative_prompt_textbox,
+ sampler_dropdown,
+ sample_step_slider,
+ resize_method,
+ width_slider,
+ height_slider,
+ base_resolution,
+ generation_method,
+ length_slider,
+ overlap_video_length,
+ partial_video_length,
+ cfg_scale_slider,
+ start_image,
+ end_image,
+ validation_video,
+ denoise_strength,
+ seed_textbox,
+ ],
+ outputs=[result_image, result_video, infer_progress]
+ )
+ return demo, controller
+
+
+def post_eas(
+ diffusion_transformer_dropdown,
+ base_model_dropdown, lora_model_dropdown, lora_alpha_slider,
+ prompt_textbox, negative_prompt_textbox,
+ sampler_dropdown, sample_step_slider, resize_method, width_slider, height_slider,
+ base_resolution, generation_method, length_slider, cfg_scale_slider,
+ start_image, end_image, validation_video, denoise_strength, seed_textbox,
+):
+ if start_image is not None:
+ with open(start_image, 'rb') as file:
+ file_content = file.read()
+ start_image_encoded_content = base64.b64encode(file_content)
+ start_image = start_image_encoded_content.decode('utf-8')
+
+ if end_image is not None:
+ with open(end_image, 'rb') as file:
+ file_content = file.read()
+ end_image_encoded_content = base64.b64encode(file_content)
+ end_image = end_image_encoded_content.decode('utf-8')
+
+ if validation_video is not None:
+ with open(validation_video, 'rb') as file:
+ file_content = file.read()
+ validation_video_encoded_content = base64.b64encode(file_content)
+ validation_video = validation_video_encoded_content.decode('utf-8')
+
+ datas = {
+ "base_model_path": base_model_dropdown,
+ "lora_model_path": lora_model_dropdown,
+ "lora_alpha_slider": lora_alpha_slider,
+ "prompt_textbox": prompt_textbox,
+ "negative_prompt_textbox": negative_prompt_textbox,
+ "sampler_dropdown": sampler_dropdown,
+ "sample_step_slider": sample_step_slider,
+ "resize_method": resize_method,
+ "width_slider": width_slider,
+ "height_slider": height_slider,
+ "base_resolution": base_resolution,
+ "generation_method": generation_method,
+ "length_slider": length_slider,
+ "cfg_scale_slider": cfg_scale_slider,
+ "start_image": start_image,
+ "end_image": end_image,
+ "validation_video": validation_video,
+ "denoise_strength": denoise_strength,
+ "seed_textbox": seed_textbox,
+ }
+
+ session = requests.session()
+ session.headers.update({"Authorization": os.environ.get("EAS_TOKEN")})
+
+ response = session.post(url=f'{os.environ.get("EAS_URL")}/cogvideox_fun/infer_forward', json=datas, timeout=300)
+
+ outputs = response.json()
+ return outputs
+
+
+class CogVideoX_I2VController_EAS:
+ def __init__(self, edition, config_path, model_name, savedir_sample):
+ self.savedir_sample = savedir_sample
+ os.makedirs(self.savedir_sample, exist_ok=True)
+
+ def generate(
+ self,
+ diffusion_transformer_dropdown,
+ base_model_dropdown,
+ lora_model_dropdown,
+ lora_alpha_slider,
+ prompt_textbox,
+ negative_prompt_textbox,
+ sampler_dropdown,
+ sample_step_slider,
+ resize_method,
+ width_slider,
+ height_slider,
+ base_resolution,
+ generation_method,
+ length_slider,
+ cfg_scale_slider,
+ start_image,
+ end_image,
+ validation_video,
+ denoise_strength,
+ seed_textbox
+ ):
+ is_image = True if generation_method == "Image Generation" else False
+
+ outputs = post_eas(
+ diffusion_transformer_dropdown,
+ base_model_dropdown, lora_model_dropdown, lora_alpha_slider,
+ prompt_textbox, negative_prompt_textbox,
+ sampler_dropdown, sample_step_slider, resize_method, width_slider, height_slider,
+ base_resolution, generation_method, length_slider, cfg_scale_slider,
+ start_image, end_image, validation_video, denoise_strength,
+ seed_textbox
+ )
+ try:
+ base64_encoding = outputs["base64_encoding"]
+ except:
+ return gr.Image(visible=False, value=None), gr.Video(None, visible=True), outputs["message"]
+
+ decoded_data = base64.b64decode(base64_encoding)
+
+ if not os.path.exists(self.savedir_sample):
+ os.makedirs(self.savedir_sample, exist_ok=True)
+ index = len([path for path in os.listdir(self.savedir_sample)]) + 1
+ prefix = str(index).zfill(3)
+
+ if is_image or length_slider == 1:
+ save_sample_path = os.path.join(self.savedir_sample, prefix + f".png")
+ with open(save_sample_path, "wb") as file:
+ file.write(decoded_data)
+ if gradio_version_is_above_4:
+ return gr.Image(value=save_sample_path, visible=True), gr.Video(value=None, visible=False), "Success"
+ else:
+ return gr.Image.update(value=save_sample_path, visible=True), gr.Video.update(value=None, visible=False), "Success"
+ else:
+ save_sample_path = os.path.join(self.savedir_sample, prefix + f".mp4")
+ with open(save_sample_path, "wb") as file:
+ file.write(decoded_data)
+ if gradio_version_is_above_4:
+ return gr.Image(visible=False, value=None), gr.Video(value=save_sample_path, visible=True), "Success"
+ else:
+ return gr.Image.update(visible=False, value=None), gr.Video.update(value=save_sample_path, visible=True), "Success"
+
+
+def ui_eas(model_name, savedir_sample):
+ controller = CogVideoX_I2VController_EAS(model_name, savedir_sample)
+
+ with gr.Blocks(css=css) as demo:
+ gr.Markdown(
+ """
+ # CogVideoX-Arbitrary
+
+ A CogVideoX with more flexible generation conditions, capable of producing videos of different resolutions, around 6 seconds, and fps 8 (frames 1 to 49), as well as image generated videos.
+
+ [Github](https://github.com/aigc-apps/CogVideoX-Arbitrary/)
+ """
+ )
+ with gr.Column(variant="panel"):
+ gr.Markdown(
+ """
+ ### 1. Model checkpoints.
+ """
+ )
+ with gr.Row():
+ diffusion_transformer_dropdown = gr.Dropdown(
+ label="Pretrained Model Path",
+ choices=[model_name],
+ value=model_name,
+ interactive=False,
+ )
+ with gr.Row():
+ base_model_dropdown = gr.Dropdown(
+ label="Select base Dreambooth model",
+ choices=["none"],
+ value="none",
+ interactive=False,
+ visible=False
+ )
+ with gr.Column(visible=False):
+ gr.Markdown(
+ """
+ ### Minimalism is an example portrait of Lora, triggered by specific prompt words. More details can be found on [Wiki](https://github.com/aigc-apps/CogVideoX-Arbitrary/wiki/Training-Lora).
+ """
+ )
+ with gr.Row():
+ lora_model_dropdown = gr.Dropdown(
+ label="Select LoRA model",
+ choices=["none"],
+ value="none",
+ interactive=True,
+ )
+
+ lora_alpha_slider = gr.Slider(label="LoRA alpha (LoRA权重)", value=0.55, minimum=0, maximum=2, interactive=True)
+
+ with gr.Column(variant="panel"):
+ gr.Markdown(
+ """
+ ### 2. Configs for Generation.
+ """
+ )
+
+ prompt_textbox = gr.Textbox(label="Prompt", lines=2, value="A young woman with beautiful and clear eyes and blonde hair standing and white dress in a forest wearing a crown. She seems to be lost in thought, and the camera focuses on her face. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.")
+ negative_prompt_textbox = gr.Textbox(label="Negative prompt", lines=2, value="The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion. " )
+
+ with gr.Row():
+ with gr.Column():
+ with gr.Row():
+ sampler_dropdown = gr.Dropdown(label="Sampling method", choices=list(scheduler_dict.keys()), value=list(scheduler_dict.keys())[0])
+ sample_step_slider = gr.Slider(label="Sampling steps", value=20, minimum=10, maximum=30, step=1, interactive=False)
+
+ resize_method = gr.Radio(
+ ["Generate by", "Resize according to Reference"],
+ value="Generate by",
+ show_label=False,
+ )
+ width_slider = gr.Slider(label="Width (视频宽度)", value=672, minimum=128, maximum=1280, step=16, interactive=False)
+ height_slider = gr.Slider(label="Height (视频高度)", value=384, minimum=128, maximum=1280, step=16, interactive=False)
+ base_resolution = gr.Radio(label="Base Resolution of Pretrained Models", value=512, choices=[512, 768, 960], interactive=False, visible=False)
+
+ with gr.Group():
+ generation_method = gr.Radio(
+ ["Video Generation", "Image Generation"],
+ value="Video Generation",
+ show_label=False,
+ visible=True,
+ )
+ length_slider = gr.Slider(label="Animation length (视频帧数)", value=49, minimum=5, maximum=49, step=4)
+
+ source_method = gr.Radio(
+ ["Text to Video (文本到视频)", "Image to Video (图片到视频)", "Video to Video (视频到视频)"],
+ value="Text to Video (文本到视频)",
+ show_label=False,
+ )
+ with gr.Column(visible = False) as image_to_video_col:
+ start_image = gr.Image(label="The image at the beginning of the video", show_label=True, elem_id="i2v_start", sources="upload", type="filepath")
+
+ template_gallery_path = ["asset/1.png", "asset/2.png", "asset/3.png", "asset/4.png", "asset/5.png"]
+ def select_template(evt: gr.SelectData):
+ text = {
+ "asset/1.png": "The dog is looking at camera and smiling. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ "asset/2.png": "a sailboat sailing in rough seas with a dramatic sunset. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ "asset/3.png": "a beautiful woman with long hair and a dress blowing in the wind. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ "asset/4.png": "a man in an astronaut suit playing a guitar. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ "asset/5.png": "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic.",
+ }[template_gallery_path[evt.index]]
+ return template_gallery_path[evt.index], text
+
+ template_gallery = gr.Gallery(
+ template_gallery_path,
+ columns=5, rows=1,
+ height=140,
+ allow_preview=False,
+ container=False,
+ label="Template Examples",
+ )
+ template_gallery.select(select_template, None, [start_image, prompt_textbox])
+
+ with gr.Accordion("The image at the ending of the video (Optional)", open=False):
+ end_image = gr.Image(label="The image at the ending of the video (Optional)", show_label=True, elem_id="i2v_end", sources="upload", type="filepath")
+
+ with gr.Column(visible = False) as video_to_video_col:
+ validation_video = gr.Video(
+ label="The video to convert (视频转视频的参考视频)", show_label=True,
+ elem_id="v2v", sources="upload",
+ )
+ denoise_strength = gr.Slider(label="Denoise strength (重绘系数)", value=0.70, minimum=0.10, maximum=0.95, step=0.01)
+
+ cfg_scale_slider = gr.Slider(label="CFG Scale (引导系数)", value=7.0, minimum=0, maximum=20)
+
+ with gr.Row():
+ seed_textbox = gr.Textbox(label="Seed", value=43)
+ seed_button = gr.Button(value="\U0001F3B2", elem_classes="toolbutton")
+ seed_button.click(
+ fn=lambda: gr.Textbox(value=random.randint(1, 1e8)) if gradio_version_is_above_4 else gr.Textbox.update(value=random.randint(1, 1e8)),
+ inputs=[],
+ outputs=[seed_textbox]
+ )
+
+ generate_button = gr.Button(value="Generate", variant='primary')
+
+ with gr.Column():
+ result_image = gr.Image(label="Generated Image", interactive=False, visible=False)
+ result_video = gr.Video(label="Generated Animation", interactive=False)
+ infer_progress = gr.Textbox(
+ label="Generation Info",
+ value="No task currently",
+ interactive=False
+ )
+
+ def upload_generation_method(generation_method):
+ if generation_method == "Video Generation":
+ return gr.update(visible=True, minimum=5, maximum=49, value=49, interactive=True)
+ elif generation_method == "Image Generation":
+ return gr.update(minimum=1, maximum=1, value=1, interactive=False)
+ generation_method.change(
+ upload_generation_method, generation_method, [length_slider]
+ )
+
+ def upload_source_method(source_method):
+ if source_method == "Text to Video (文本到视频)":
+ return [gr.update(visible=False), gr.update(visible=False), gr.update(value=None), gr.update(value=None), gr.update(value=None)]
+ elif source_method == "Image to Video (图片到视频)":
+ return [gr.update(visible=True), gr.update(visible=False), gr.update(), gr.update(), gr.update(value=None)]
+ else:
+ return [gr.update(visible=False), gr.update(visible=True), gr.update(value=None), gr.update(value=None), gr.update()]
+ source_method.change(
+ upload_source_method, source_method, [image_to_video_col, video_to_video_col, start_image, end_image, validation_video]
+ )
+
+ def upload_resize_method(resize_method):
+ if resize_method == "Generate by":
+ return [gr.update(visible=True), gr.update(visible=True), gr.update(visible=False)]
+ else:
+ return [gr.update(visible=False), gr.update(visible=False), gr.update(visible=True)]
+ resize_method.change(
+ upload_resize_method, resize_method, [width_slider, height_slider, base_resolution]
+ )
+
+ generate_button.click(
+ fn=controller.generate,
+ inputs=[
+ diffusion_transformer_dropdown,
+ base_model_dropdown,
+ lora_model_dropdown,
+ lora_alpha_slider,
+ prompt_textbox,
+ negative_prompt_textbox,
+ sampler_dropdown,
+ sample_step_slider,
+ resize_method,
+ width_slider,
+ height_slider,
+ base_resolution,
+ generation_method,
+ length_slider,
+ cfg_scale_slider,
+ start_image,
+ end_image,
+ validation_video,
+ denoise_strength,
+ seed_textbox,
+ ],
+ outputs=[result_image, result_video, infer_progress]
+ )
+ return demo, controller
\ No newline at end of file
diff --git a/cogvideox/utils/__init__.py b/cogvideox/utils/__init__.py
new file mode 100644
index 0000000..e69de29
diff --git a/cogvideox/utils/lora_utils.py b/cogvideox/utils/lora_utils.py
new file mode 100644
index 0000000..37b51fc
--- /dev/null
+++ b/cogvideox/utils/lora_utils.py
@@ -0,0 +1,477 @@
+# LoRA network module
+# reference:
+# https://github.com/microsoft/LoRA/blob/main/loralib/layers.py
+# https://github.com/cloneofsimo/lora/blob/master/lora_diffusion/lora.py
+# https://github.com/bmaltais/kohya_ss
+
+import hashlib
+import math
+import os
+from collections import defaultdict
+from io import BytesIO
+from typing import List, Optional, Type, Union
+
+import safetensors.torch
+import torch
+import torch.utils.checkpoint
+from diffusers.models.lora import LoRACompatibleConv, LoRACompatibleLinear
+from safetensors.torch import load_file
+from transformers import T5EncoderModel
+
+
+class LoRAModule(torch.nn.Module):
+ """
+ replaces forward method of the original Linear, instead of replacing the original Linear module.
+ """
+
+ def __init__(
+ self,
+ lora_name,
+ org_module: torch.nn.Module,
+ multiplier=1.0,
+ lora_dim=4,
+ alpha=1,
+ dropout=None,
+ rank_dropout=None,
+ module_dropout=None,
+ ):
+ """if alpha == 0 or None, alpha is rank (no scaling)."""
+ super().__init__()
+ self.lora_name = lora_name
+
+ if org_module.__class__.__name__ == "Conv2d":
+ in_dim = org_module.in_channels
+ out_dim = org_module.out_channels
+ else:
+ in_dim = org_module.in_features
+ out_dim = org_module.out_features
+
+ self.lora_dim = lora_dim
+ if org_module.__class__.__name__ == "Conv2d":
+ kernel_size = org_module.kernel_size
+ stride = org_module.stride
+ padding = org_module.padding
+ self.lora_down = torch.nn.Conv2d(in_dim, self.lora_dim, kernel_size, stride, padding, bias=False)
+ self.lora_up = torch.nn.Conv2d(self.lora_dim, out_dim, (1, 1), (1, 1), bias=False)
+ else:
+ self.lora_down = torch.nn.Linear(in_dim, self.lora_dim, bias=False)
+ self.lora_up = torch.nn.Linear(self.lora_dim, out_dim, bias=False)
+
+ if type(alpha) == torch.Tensor:
+ alpha = alpha.detach().float().numpy() # without casting, bf16 causes error
+ alpha = self.lora_dim if alpha is None or alpha == 0 else alpha
+ self.scale = alpha / self.lora_dim
+ self.register_buffer("alpha", torch.tensor(alpha))
+
+ # same as microsoft's
+ torch.nn.init.kaiming_uniform_(self.lora_down.weight, a=math.sqrt(5))
+ torch.nn.init.zeros_(self.lora_up.weight)
+
+ self.multiplier = multiplier
+ self.org_module = org_module # remove in applying
+ self.dropout = dropout
+ self.rank_dropout = rank_dropout
+ self.module_dropout = module_dropout
+
+ def apply_to(self):
+ self.org_forward = self.org_module.forward
+ self.org_module.forward = self.forward
+ del self.org_module
+
+ def forward(self, x, *args, **kwargs):
+ weight_dtype = x.dtype
+ org_forwarded = self.org_forward(x)
+
+ # module dropout
+ if self.module_dropout is not None and self.training:
+ if torch.rand(1) < self.module_dropout:
+ return org_forwarded
+
+ lx = self.lora_down(x.to(self.lora_down.weight.dtype))
+
+ # normal dropout
+ if self.dropout is not None and self.training:
+ lx = torch.nn.functional.dropout(lx, p=self.dropout)
+
+ # rank dropout
+ if self.rank_dropout is not None and self.training:
+ mask = torch.rand((lx.size(0), self.lora_dim), device=lx.device) > self.rank_dropout
+ if len(lx.size()) == 3:
+ mask = mask.unsqueeze(1) # for Text Encoder
+ elif len(lx.size()) == 4:
+ mask = mask.unsqueeze(-1).unsqueeze(-1) # for Conv2d
+ lx = lx * mask
+
+ # scaling for rank dropout: treat as if the rank is changed
+ scale = self.scale * (1.0 / (1.0 - self.rank_dropout)) # redundant for readability
+ else:
+ scale = self.scale
+
+ lx = self.lora_up(lx)
+
+ return org_forwarded.to(weight_dtype) + lx.to(weight_dtype) * self.multiplier * scale
+
+
+def addnet_hash_legacy(b):
+ """Old model hash used by sd-webui-additional-networks for .safetensors format files"""
+ m = hashlib.sha256()
+
+ b.seek(0x100000)
+ m.update(b.read(0x10000))
+ return m.hexdigest()[0:8]
+
+
+def addnet_hash_safetensors(b):
+ """New model hash used by sd-webui-additional-networks for .safetensors format files"""
+ hash_sha256 = hashlib.sha256()
+ blksize = 1024 * 1024
+
+ b.seek(0)
+ header = b.read(8)
+ n = int.from_bytes(header, "little")
+
+ offset = n + 8
+ b.seek(offset)
+ for chunk in iter(lambda: b.read(blksize), b""):
+ hash_sha256.update(chunk)
+
+ return hash_sha256.hexdigest()
+
+
+def precalculate_safetensors_hashes(tensors, metadata):
+ """Precalculate the model hashes needed by sd-webui-additional-networks to
+ save time on indexing the model later."""
+
+ # Because writing user metadata to the file can change the result of
+ # sd_models.model_hash(), only retain the training metadata for purposes of
+ # calculating the hash, as they are meant to be immutable
+ metadata = {k: v for k, v in metadata.items() if k.startswith("ss_")}
+
+ bytes = safetensors.torch.save(tensors, metadata)
+ b = BytesIO(bytes)
+
+ model_hash = addnet_hash_safetensors(b)
+ legacy_hash = addnet_hash_legacy(b)
+ return model_hash, legacy_hash
+
+
+class LoRANetwork(torch.nn.Module):
+ TRANSFORMER_TARGET_REPLACE_MODULE = ["CogVideoXTransformer3DModel"]
+ TEXT_ENCODER_TARGET_REPLACE_MODULE = ["T5LayerSelfAttention", "T5LayerFF", "BertEncoder"]
+ LORA_PREFIX_TRANSFORMER = "lora_unet"
+ LORA_PREFIX_TEXT_ENCODER = "lora_te"
+ def __init__(
+ self,
+ text_encoder: Union[List[T5EncoderModel], T5EncoderModel],
+ unet,
+ multiplier: float = 1.0,
+ lora_dim: int = 4,
+ alpha: float = 1,
+ dropout: Optional[float] = None,
+ module_class: Type[object] = LoRAModule,
+ add_lora_in_attn_temporal: bool = False,
+ varbose: Optional[bool] = False,
+ ) -> None:
+ super().__init__()
+ self.multiplier = multiplier
+
+ self.lora_dim = lora_dim
+ self.alpha = alpha
+ self.dropout = dropout
+
+ print(f"create LoRA network. base dim (rank): {lora_dim}, alpha: {alpha}")
+ print(f"neuron dropout: p={self.dropout}")
+
+ # create module instances
+ def create_modules(
+ is_unet: bool,
+ root_module: torch.nn.Module,
+ target_replace_modules: List[torch.nn.Module],
+ ) -> List[LoRAModule]:
+ prefix = (
+ self.LORA_PREFIX_TRANSFORMER
+ if is_unet
+ else self.LORA_PREFIX_TEXT_ENCODER
+ )
+ loras = []
+ skipped = []
+ for name, module in root_module.named_modules():
+ if module.__class__.__name__ in target_replace_modules:
+ for child_name, child_module in module.named_modules():
+ is_linear = child_module.__class__.__name__ == "Linear" or child_module.__class__.__name__ == "LoRACompatibleLinear"
+ is_conv2d = child_module.__class__.__name__ == "Conv2d" or child_module.__class__.__name__ == "LoRACompatibleConv"
+ is_conv2d_1x1 = is_conv2d and child_module.kernel_size == (1, 1)
+
+ if not add_lora_in_attn_temporal:
+ if "attn_temporal" in child_name:
+ continue
+
+ if is_linear or is_conv2d:
+ lora_name = prefix + "." + name + "." + child_name
+ lora_name = lora_name.replace(".", "_")
+
+ dim = None
+ alpha = None
+
+ if is_linear or is_conv2d_1x1:
+ dim = self.lora_dim
+ alpha = self.alpha
+
+ if dim is None or dim == 0:
+ if is_linear or is_conv2d_1x1:
+ skipped.append(lora_name)
+ continue
+
+ lora = module_class(
+ lora_name,
+ child_module,
+ self.multiplier,
+ dim,
+ alpha,
+ dropout=dropout,
+ )
+ loras.append(lora)
+ return loras, skipped
+
+ text_encoders = text_encoder if type(text_encoder) == list else [text_encoder]
+
+ self.text_encoder_loras = []
+ skipped_te = []
+ for i, text_encoder in enumerate(text_encoders):
+ if text_encoder is not None:
+ text_encoder_loras, skipped = create_modules(False, text_encoder, LoRANetwork.TEXT_ENCODER_TARGET_REPLACE_MODULE)
+ self.text_encoder_loras.extend(text_encoder_loras)
+ skipped_te += skipped
+ print(f"create LoRA for Text Encoder: {len(self.text_encoder_loras)} modules.")
+
+ self.unet_loras, skipped_un = create_modules(True, unet, LoRANetwork.TRANSFORMER_TARGET_REPLACE_MODULE)
+ print(f"create LoRA for U-Net: {len(self.unet_loras)} modules.")
+
+ # assertion
+ names = set()
+ for lora in self.text_encoder_loras + self.unet_loras:
+ assert lora.lora_name not in names, f"duplicated lora name: {lora.lora_name}"
+ names.add(lora.lora_name)
+
+ def apply_to(self, text_encoder, unet, apply_text_encoder=True, apply_unet=True):
+ if apply_text_encoder:
+ print("enable LoRA for text encoder")
+ else:
+ self.text_encoder_loras = []
+
+ if apply_unet:
+ print("enable LoRA for U-Net")
+ else:
+ self.unet_loras = []
+
+ for lora in self.text_encoder_loras + self.unet_loras:
+ lora.apply_to()
+ self.add_module(lora.lora_name, lora)
+
+ def set_multiplier(self, multiplier):
+ self.multiplier = multiplier
+ for lora in self.text_encoder_loras + self.unet_loras:
+ lora.multiplier = self.multiplier
+
+ def load_weights(self, file):
+ if os.path.splitext(file)[1] == ".safetensors":
+ from safetensors.torch import load_file
+
+ weights_sd = load_file(file)
+ else:
+ weights_sd = torch.load(file, map_location="cpu")
+ info = self.load_state_dict(weights_sd, False)
+ return info
+
+ def prepare_optimizer_params(self, text_encoder_lr, unet_lr, default_lr):
+ self.requires_grad_(True)
+ all_params = []
+
+ def enumerate_params(loras):
+ params = []
+ for lora in loras:
+ params.extend(lora.parameters())
+ return params
+
+ if self.text_encoder_loras:
+ param_data = {"params": enumerate_params(self.text_encoder_loras)}
+ if text_encoder_lr is not None:
+ param_data["lr"] = text_encoder_lr
+ all_params.append(param_data)
+
+ if self.unet_loras:
+ param_data = {"params": enumerate_params(self.unet_loras)}
+ if unet_lr is not None:
+ param_data["lr"] = unet_lr
+ all_params.append(param_data)
+
+ return all_params
+
+ def enable_gradient_checkpointing(self):
+ pass
+
+ def get_trainable_params(self):
+ return self.parameters()
+
+ def save_weights(self, file, dtype, metadata):
+ if metadata is not None and len(metadata) == 0:
+ metadata = None
+
+ state_dict = self.state_dict()
+
+ if dtype is not None:
+ for key in list(state_dict.keys()):
+ v = state_dict[key]
+ v = v.detach().clone().to("cpu").to(dtype)
+ state_dict[key] = v
+
+ if os.path.splitext(file)[1] == ".safetensors":
+ from safetensors.torch import save_file
+
+ # Precalculate model hashes to save time on indexing
+ if metadata is None:
+ metadata = {}
+ model_hash, legacy_hash = precalculate_safetensors_hashes(state_dict, metadata)
+ metadata["sshs_model_hash"] = model_hash
+ metadata["sshs_legacy_hash"] = legacy_hash
+
+ save_file(state_dict, file, metadata)
+ else:
+ torch.save(state_dict, file)
+
+def create_network(
+ multiplier: float,
+ network_dim: Optional[int],
+ network_alpha: Optional[float],
+ text_encoder: Union[T5EncoderModel, List[T5EncoderModel]],
+ transformer,
+ neuron_dropout: Optional[float] = None,
+ add_lora_in_attn_temporal: bool = False,
+ **kwargs,
+):
+ if network_dim is None:
+ network_dim = 4 # default
+ if network_alpha is None:
+ network_alpha = 1.0
+
+ network = LoRANetwork(
+ text_encoder,
+ transformer,
+ multiplier=multiplier,
+ lora_dim=network_dim,
+ alpha=network_alpha,
+ dropout=neuron_dropout,
+ add_lora_in_attn_temporal=add_lora_in_attn_temporal,
+ varbose=True,
+ )
+ return network
+
+def merge_lora(pipeline, lora_path, multiplier, device='cpu', dtype=torch.float32, state_dict=None, transformer_only=False):
+ LORA_PREFIX_TRANSFORMER = "lora_unet"
+ LORA_PREFIX_TEXT_ENCODER = "lora_te"
+ if state_dict is None:
+ state_dict = load_file(lora_path, device=device)
+ else:
+ state_dict = state_dict
+ updates = defaultdict(dict)
+ for key, value in state_dict.items():
+ layer, elem = key.split('.', 1)
+ updates[layer][elem] = value
+
+ for layer, elems in updates.items():
+
+ if "lora_te" in layer:
+ if transformer_only:
+ continue
+ else:
+ layer_infos = layer.split(LORA_PREFIX_TEXT_ENCODER + "_")[-1].split("_")
+ curr_layer = pipeline.text_encoder
+ else:
+ layer_infos = layer.split(LORA_PREFIX_TRANSFORMER + "_")[-1].split("_")
+ curr_layer = pipeline.transformer
+
+ temp_name = layer_infos.pop(0)
+ while len(layer_infos) > -1:
+ try:
+ curr_layer = curr_layer.__getattr__(temp_name)
+ if len(layer_infos) > 0:
+ temp_name = layer_infos.pop(0)
+ elif len(layer_infos) == 0:
+ break
+ except Exception:
+ if len(layer_infos) == 0:
+ print('Error loading layer')
+ if len(temp_name) > 0:
+ temp_name += "_" + layer_infos.pop(0)
+ else:
+ temp_name = layer_infos.pop(0)
+
+ weight_up = elems['lora_up.weight'].to(dtype)
+ weight_down = elems['lora_down.weight'].to(dtype)
+ if 'alpha' in elems.keys():
+ alpha = elems['alpha'].item() / weight_up.shape[1]
+ else:
+ alpha = 1.0
+
+ curr_layer.weight.data = curr_layer.weight.data.to(device)
+ if len(weight_up.shape) == 4:
+ curr_layer.weight.data += multiplier * alpha * torch.mm(weight_up.squeeze(3).squeeze(2),
+ weight_down.squeeze(3).squeeze(2)).unsqueeze(
+ 2).unsqueeze(3)
+ else:
+ curr_layer.weight.data += multiplier * alpha * torch.mm(weight_up, weight_down)
+
+ return pipeline
+
+# TODO: Refactor with merge_lora.
+def unmerge_lora(pipeline, lora_path, multiplier=1, device="cpu", dtype=torch.float32):
+ """Unmerge state_dict in LoRANetwork from the pipeline in diffusers."""
+ LORA_PREFIX_UNET = "lora_unet"
+ LORA_PREFIX_TEXT_ENCODER = "lora_te"
+ state_dict = load_file(lora_path, device=device)
+
+ updates = defaultdict(dict)
+ for key, value in state_dict.items():
+ layer, elem = key.split('.', 1)
+ updates[layer][elem] = value
+
+ for layer, elems in updates.items():
+
+ if "lora_te" in layer:
+ layer_infos = layer.split(LORA_PREFIX_TEXT_ENCODER + "_")[-1].split("_")
+ curr_layer = pipeline.text_encoder
+ else:
+ layer_infos = layer.split(LORA_PREFIX_UNET + "_")[-1].split("_")
+ curr_layer = pipeline.transformer
+
+ temp_name = layer_infos.pop(0)
+ while len(layer_infos) > -1:
+ try:
+ curr_layer = curr_layer.__getattr__(temp_name)
+ if len(layer_infos) > 0:
+ temp_name = layer_infos.pop(0)
+ elif len(layer_infos) == 0:
+ break
+ except Exception:
+ if len(layer_infos) == 0:
+ print('Error loading layer')
+ if len(temp_name) > 0:
+ temp_name += "_" + layer_infos.pop(0)
+ else:
+ temp_name = layer_infos.pop(0)
+
+ weight_up = elems['lora_up.weight'].to(dtype)
+ weight_down = elems['lora_down.weight'].to(dtype)
+ if 'alpha' in elems.keys():
+ alpha = elems['alpha'].item() / weight_up.shape[1]
+ else:
+ alpha = 1.0
+
+ curr_layer.weight.data = curr_layer.weight.data.to(device)
+ if len(weight_up.shape) == 4:
+ curr_layer.weight.data -= multiplier * alpha * torch.mm(weight_up.squeeze(3).squeeze(2),
+ weight_down.squeeze(3).squeeze(2)).unsqueeze(2).unsqueeze(3)
+ else:
+ curr_layer.weight.data -= multiplier * alpha * torch.mm(weight_up, weight_down)
+
+ return pipeline
\ No newline at end of file
diff --git a/cogvideox/utils/utils.py b/cogvideox/utils/utils.py
new file mode 100644
index 0000000..c273216
--- /dev/null
+++ b/cogvideox/utils/utils.py
@@ -0,0 +1,189 @@
+import os
+import gc
+import imageio
+import numpy as np
+import torch
+import torchvision
+import cv2
+from einops import rearrange
+from PIL import Image
+
+def get_width_and_height_from_image_and_base_resolution(image, base_resolution):
+ target_pixels = int(base_resolution) * int(base_resolution)
+ original_width, original_height = Image.open(image).size
+ ratio = (target_pixels / (original_width * original_height)) ** 0.5
+ width_slider = round(original_width * ratio)
+ height_slider = round(original_height * ratio)
+ return height_slider, width_slider
+
+def color_transfer(sc, dc):
+ """
+ Transfer color distribution from of sc, referred to dc.
+
+ Args:
+ sc (numpy.ndarray): input image to be transfered.
+ dc (numpy.ndarray): reference image
+
+ Returns:
+ numpy.ndarray: Transferred color distribution on the sc.
+ """
+
+ def get_mean_and_std(img):
+ x_mean, x_std = cv2.meanStdDev(img)
+ x_mean = np.hstack(np.around(x_mean, 2))
+ x_std = np.hstack(np.around(x_std, 2))
+ return x_mean, x_std
+
+ sc = cv2.cvtColor(sc, cv2.COLOR_RGB2LAB)
+ s_mean, s_std = get_mean_and_std(sc)
+ dc = cv2.cvtColor(dc, cv2.COLOR_RGB2LAB)
+ t_mean, t_std = get_mean_and_std(dc)
+ img_n = ((sc - s_mean) * (t_std / s_std)) + t_mean
+ np.putmask(img_n, img_n > 255, 255)
+ np.putmask(img_n, img_n < 0, 0)
+ dst = cv2.cvtColor(cv2.convertScaleAbs(img_n), cv2.COLOR_LAB2RGB)
+ return dst
+
+def save_videos_grid(videos: torch.Tensor, path: str, rescale=False, n_rows=6, fps=12, imageio_backend=True, color_transfer_post_process=False):
+ videos = rearrange(videos, "b c t h w -> t b c h w")
+ outputs = []
+ for x in videos:
+ x = torchvision.utils.make_grid(x, nrow=n_rows)
+ x = x.transpose(0, 1).transpose(1, 2).squeeze(-1)
+ if rescale:
+ x = (x + 1.0) / 2.0 # -1,1 -> 0,1
+ x = (x * 255).numpy().astype(np.uint8)
+ outputs.append(Image.fromarray(x))
+
+ if color_transfer_post_process:
+ for i in range(1, len(outputs)):
+ outputs[i] = Image.fromarray(color_transfer(np.uint8(outputs[i]), np.uint8(outputs[0])))
+
+ os.makedirs(os.path.dirname(path), exist_ok=True)
+ if imageio_backend:
+ if path.endswith("mp4"):
+ imageio.mimsave(path, outputs, fps=fps)
+ else:
+ imageio.mimsave(path, outputs, duration=(1000 * 1/fps))
+ else:
+ if path.endswith("mp4"):
+ path = path.replace('.mp4', '.gif')
+ outputs[0].save(path, format='GIF', append_images=outputs, save_all=True, duration=100, loop=0)
+
+def get_image_to_video_latent(validation_image_start, validation_image_end, video_length, sample_size):
+ if validation_image_start is not None and validation_image_end is not None:
+ if type(validation_image_start) is str and os.path.isfile(validation_image_start):
+ image_start = clip_image = Image.open(validation_image_start).convert("RGB")
+ image_start = image_start.resize([sample_size[1], sample_size[0]])
+ clip_image = clip_image.resize([sample_size[1], sample_size[0]])
+ else:
+ image_start = clip_image = validation_image_start
+ image_start = [_image_start.resize([sample_size[1], sample_size[0]]) for _image_start in image_start]
+ clip_image = [_clip_image.resize([sample_size[1], sample_size[0]]) for _clip_image in clip_image]
+
+ if type(validation_image_end) is str and os.path.isfile(validation_image_end):
+ image_end = Image.open(validation_image_end).convert("RGB")
+ image_end = image_end.resize([sample_size[1], sample_size[0]])
+ else:
+ image_end = validation_image_end
+ image_end = [_image_end.resize([sample_size[1], sample_size[0]]) for _image_end in image_end]
+
+ if type(image_start) is list:
+ clip_image = clip_image[0]
+ start_video = torch.cat(
+ [torch.from_numpy(np.array(_image_start)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0) for _image_start in image_start],
+ dim=2
+ )
+ input_video = torch.tile(start_video[:, :, :1], [1, 1, video_length, 1, 1])
+ input_video[:, :, :len(image_start)] = start_video
+
+ input_video_mask = torch.zeros_like(input_video[:, :1])
+ input_video_mask[:, :, len(image_start):] = 255
+ else:
+ input_video = torch.tile(
+ torch.from_numpy(np.array(image_start)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0),
+ [1, 1, video_length, 1, 1]
+ )
+ input_video_mask = torch.zeros_like(input_video[:, :1])
+ input_video_mask[:, :, 3:] = 255
+
+ if type(image_end) is list:
+ image_end = [_image_end.resize(image_start[0].size if type(image_start) is list else image_start.size) for _image_end in image_end]
+ end_video = torch.cat(
+ [torch.from_numpy(np.array(_image_end)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0) for _image_end in image_end],
+ dim=2
+ )
+ input_video[:, :, -len(end_video):] = end_video
+
+ input_video_mask[:, :, -len(image_end):] = 0
+ else:
+ image_end = image_end.resize(image_start[0].size if type(image_start) is list else image_start.size)
+ input_video[:, :, -3:] = torch.from_numpy(np.array(image_end)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0)
+ input_video_mask[:, :, -3:] = 0
+
+ input_video = input_video / 255
+
+ elif validation_image_start is not None:
+ if type(validation_image_start) is str and os.path.isfile(validation_image_start):
+ image_start = clip_image = Image.open(validation_image_start).convert("RGB")
+ image_start = image_start.resize([sample_size[1], sample_size[0]])
+ clip_image = clip_image.resize([sample_size[1], sample_size[0]])
+ else:
+ image_start = clip_image = validation_image_start
+ image_start = [_image_start.resize([sample_size[1], sample_size[0]]) for _image_start in image_start]
+ clip_image = [_clip_image.resize([sample_size[1], sample_size[0]]) for _clip_image in clip_image]
+ image_end = None
+
+ if type(image_start) is list:
+ clip_image = clip_image[0]
+ start_video = torch.cat(
+ [torch.from_numpy(np.array(_image_start)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0) for _image_start in image_start],
+ dim=2
+ )
+ input_video = torch.tile(start_video[:, :, :1], [1, 1, video_length, 1, 1])
+ input_video[:, :, :len(image_start)] = start_video
+ input_video = input_video / 255
+
+ input_video_mask = torch.zeros_like(input_video[:, :1])
+ input_video_mask[:, :, len(image_start):] = 255
+ else:
+ input_video = torch.tile(
+ torch.from_numpy(np.array(image_start)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0),
+ [1, 1, video_length, 1, 1]
+ ) / 255
+ input_video_mask = torch.zeros_like(input_video[:, :1])
+ input_video_mask[:, :, 3:, ] = 255
+ else:
+ image_start = None
+ image_end = None
+ input_video = torch.zeros([1, 3, video_length, sample_size[0], sample_size[1]])
+ input_video_mask = torch.ones([1, 1, video_length, sample_size[0], sample_size[1]]) * 255
+ clip_image = None
+
+ del image_start
+ del image_end
+ gc.collect()
+
+ return input_video, input_video_mask, clip_image
+
+def get_video_to_video_latent(input_video_path, video_length, sample_size):
+ if type(input_video_path) is str:
+ cap = cv2.VideoCapture(input_video_path)
+ input_video = []
+ while True:
+ ret, frame = cap.read()
+ if not ret:
+ break
+ frame = cv2.resize(frame, (sample_size[1], sample_size[0]))
+ input_video.append(cv2.cvtColor(frame, cv2.COLOR_BGR2RGB))
+ cap.release()
+ else:
+ input_video = input_video_path
+
+ input_video = torch.from_numpy(np.array(input_video))[:video_length]
+ input_video = input_video.permute([3, 0, 1, 2]).unsqueeze(0) / 255
+
+ input_video_mask = torch.zeros_like(input_video[:, :1])
+ input_video_mask[:, :, :] = 255
+
+ return input_video, input_video_mask, None
\ No newline at end of file
diff --git a/comfyui/README.md b/comfyui/README.md
new file mode 100644
index 0000000..d091fac
--- /dev/null
+++ b/comfyui/README.md
@@ -0,0 +1,89 @@
+# ComfyUI EasyAnimate
+Easily use EasyAnimate inside ComfyUI!
+
+[](https://arxiv.org/abs/2405.18991)
+[](https://easyanimate.github.io/)
+[](https://modelscope.cn/studios/PAI/EasyAnimate/summary)
+[](https://huggingface.co/spaces/alibaba-pai/EasyAnimate)
+
+- [Installation](#1-installation)
+- [Node types](#node-types)
+- [Example workflows](#example-workflows)
+ - [Image to video](#image-to-video)
+ - [Image to video generation (high FPS w/ frame interpolation)](#image-to-video-generation-high-fps-w-frame-interpolation)
+
+## 1. Installation
+
+### Option 1: Install via ComfyUI Manager
+TBD
+
+### Option 2: Install manually
+The EasyAnimate repository needs to be placed at `ComfyUI/custom_nodes/EasyAnimate/`.
+
+```
+cd ComfyUI/custom_nodes/
+
+# Git clone the easyanimate itself
+git clone https://github.com/aigc-apps/EasyAnimate.git
+
+# Git clone the video outout node
+git clone https://github.com/Kosinkadink/ComfyUI-VideoHelperSuite.git
+
+cd EasyAnimate/
+python install.py
+```
+
+### 2. Download models into `ComfyUI/models/EasyAnimate/`
+
+| Name | Type | Storage Space | Url | Hugging Face | Description |
+| EasyAnimateV4-XL-2-InP.tar | EasyAnimateV4 | 18.2GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/Diffusion_Transformer/EasyAnimateV4-XL-2-InP.tar) | [🤗Link](https://huggingface.co/alibaba-pai/EasyAnimateV4-XL-2-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 144 frames at a rate of 24 frames per second. |
+
+
+ (Obsolete) EasyAnimateV3:
+
+| Name | Type | Storage Space | Url | Hugging Face | Description |
+|--|--|--|--|--|--|
+| EasyAnimateV3-XL-2-InP-512x512.tar | EasyAnimateV3 | 18.2GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/Diffusion_Transformer/EasyAnimateV3-XL-2-InP-512x512.tar) | [🤗Link](https://huggingface.co/alibaba-pai/EasyAnimateV3-XL-2-InP-512x512) | EasyAnimateV3 official weights for 512x512 text and image to video resolution. Training with 144 frames and fps 24 |
+| EasyAnimateV3-XL-2-InP-768x768.tar | EasyAnimateV3 | 18.2GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/Diffusion_Transformer/EasyAnimateV3-XL-2-InP-768x768.tar) | [🤗Link](https://huggingface.co/alibaba-pai/EasyAnimateV3-XL-2-InP-768x768) | EasyAnimateV3 official weights for 768x768 text and image to video resolution. Training with 144 frames and fps 24 |
+| EasyAnimateV3-XL-2-InP-960x960.tar | EasyAnimateV3 | 18.2GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/Diffusion_Transformer/EasyAnimateV3-XL-2-InP-960x960.tar) | [🤗Link](https://huggingface.co/alibaba-pai/EasyAnimateV3-XL-2-InP-960x960) | EasyAnimateV3 official weights for 960x960 text and image to video resolution. Training with 144 frames and fps 24 |
+
+
+## Node types
+- **LoadEasyAnimateModel**
+ - Loads the EasyAnimate model
+- **TextBox**
+ - Write the prompt for EasyAnimate model
+- **EasyAnimateI2VSampler**
+ - EasyAnimate Sampler for Image to Video
+- **EasyAnimateT2VSampler**
+ - EasyAnimate Sampler for Text to Video
+- **EasyAnimateV2VSampler**
+ - EasyAnimate Sampler for Video to Video
+
+## Example workflows
+
+### Video to video generation
+Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/asset/v4/easyanimatev4_workflow_v2v.json) of the json:
+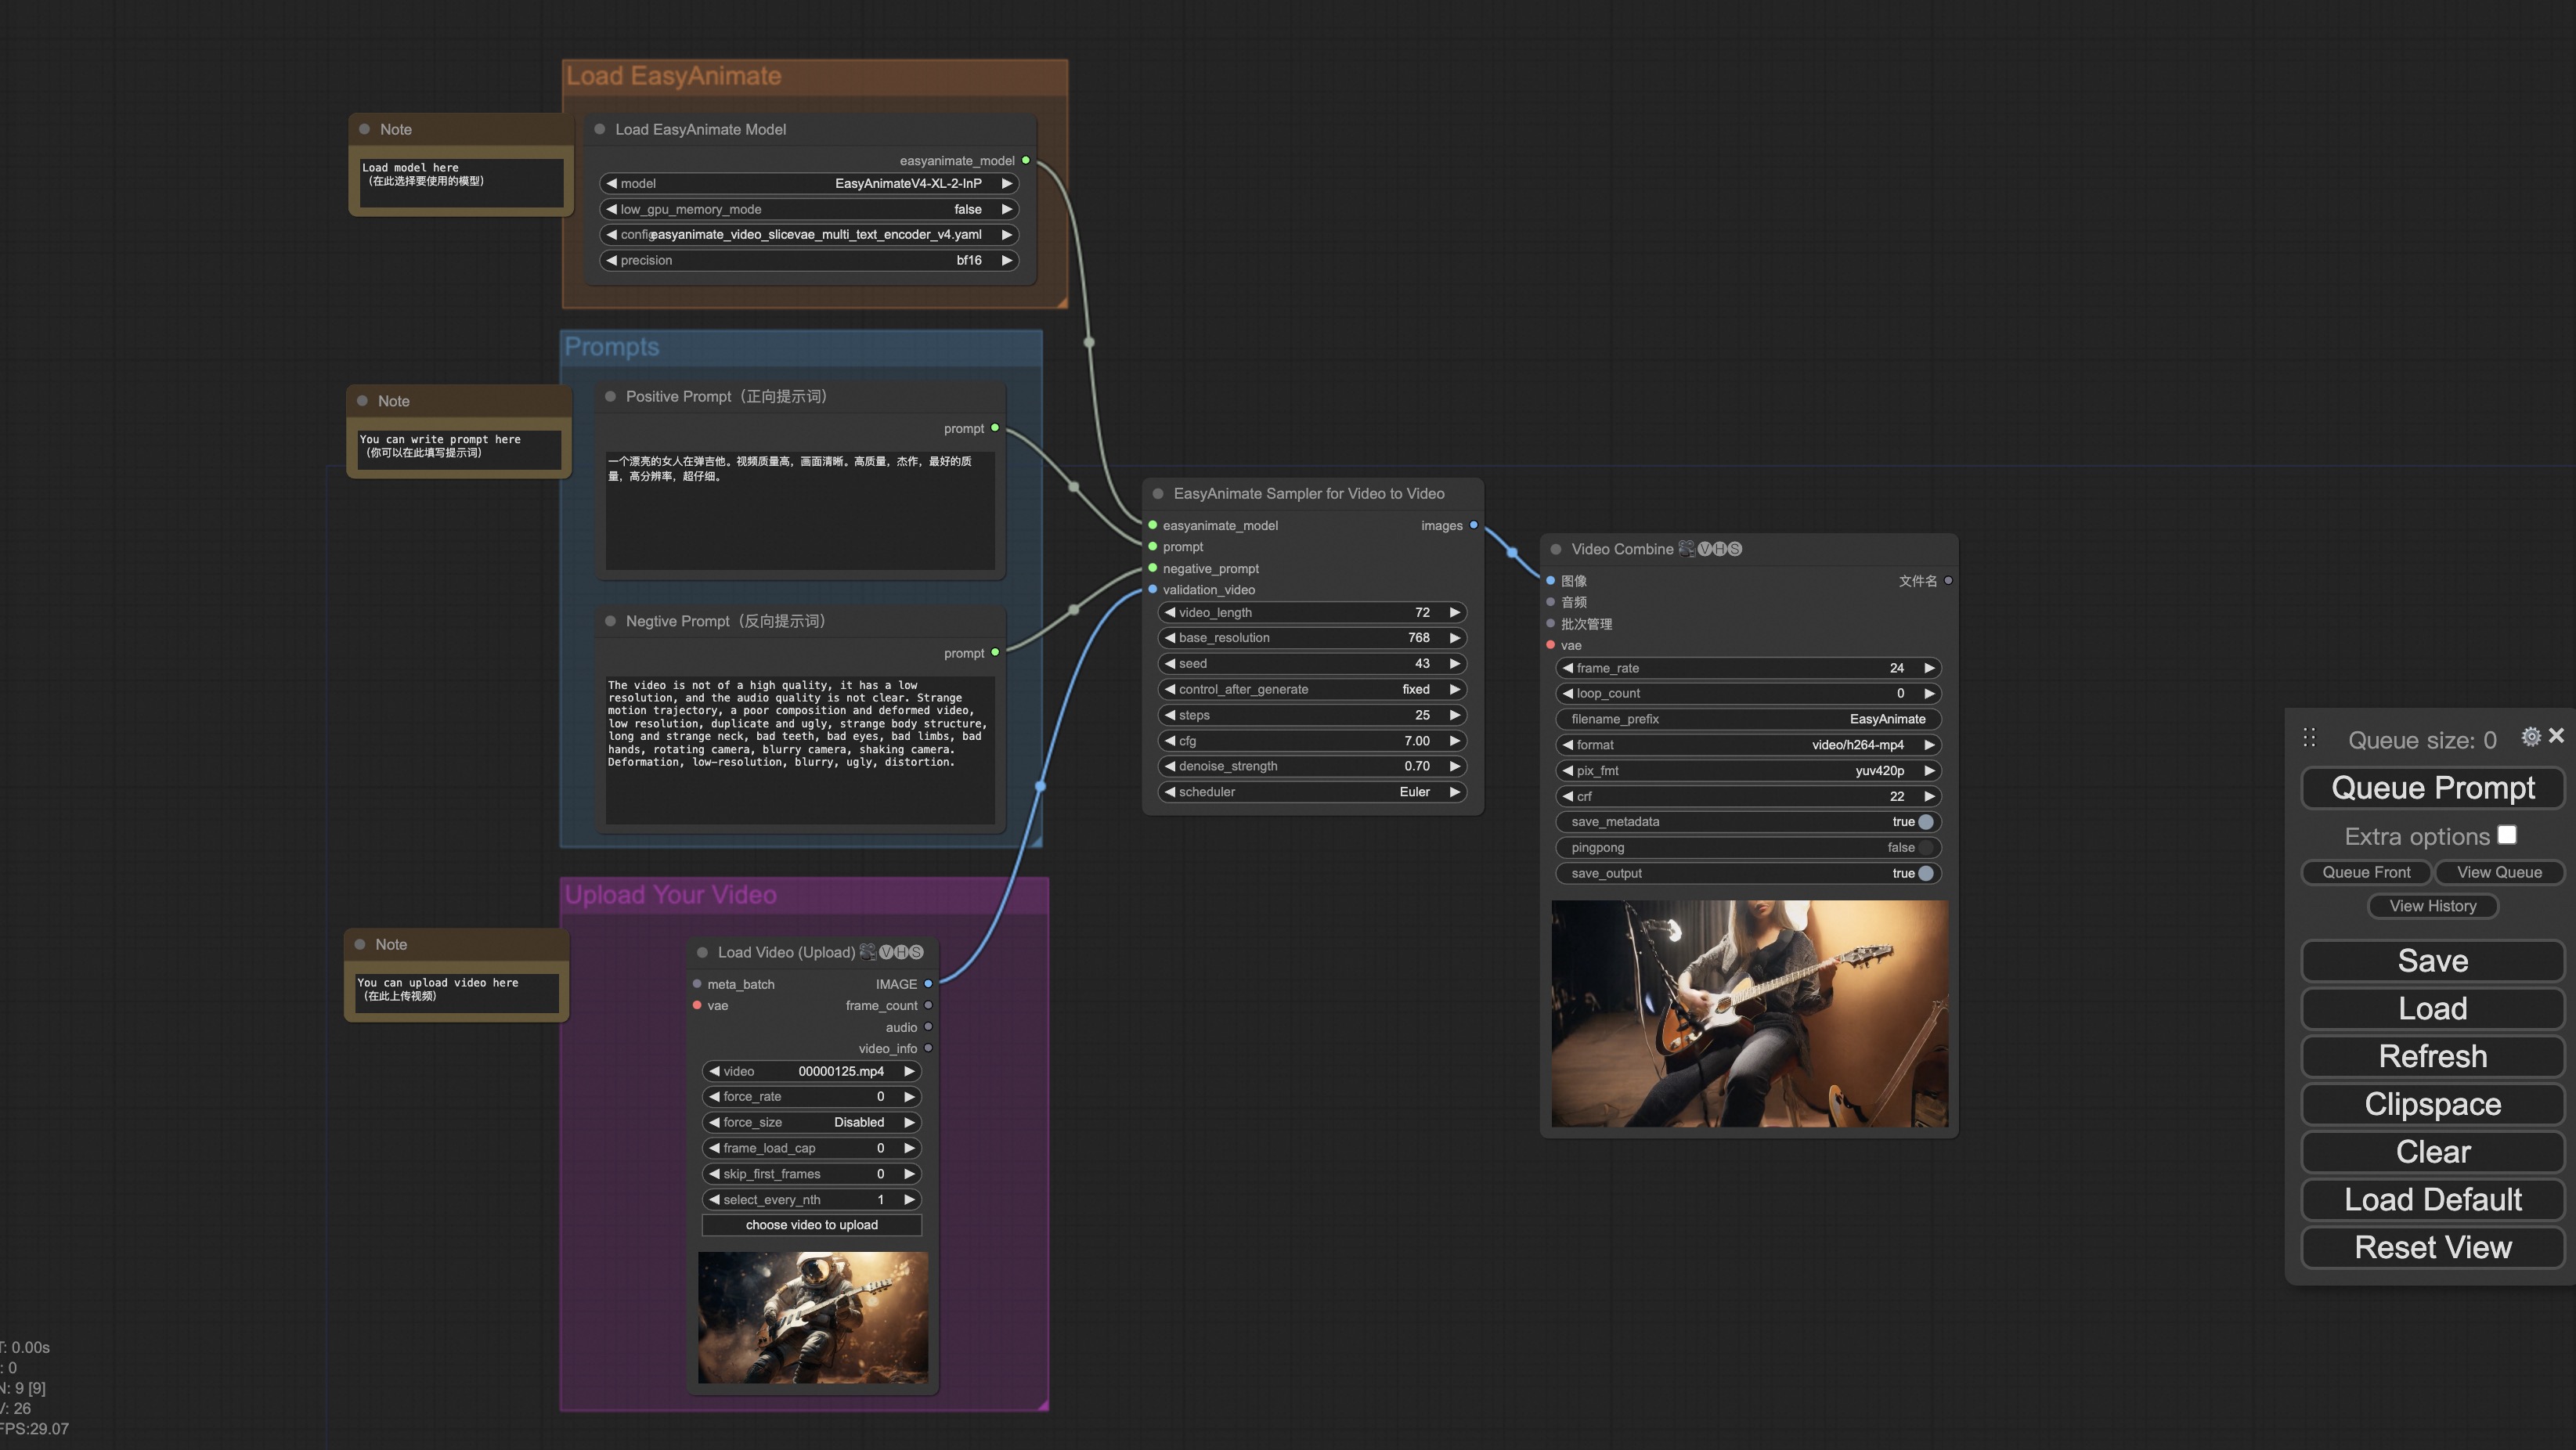
+
+You can run the demo using following video:
+[demo video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/asset/v4/play_guitar.mp4)
+
+### Image to video generation
+Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/asset/v4/easyanimatev4_workflow_i2v.json) of the json:
+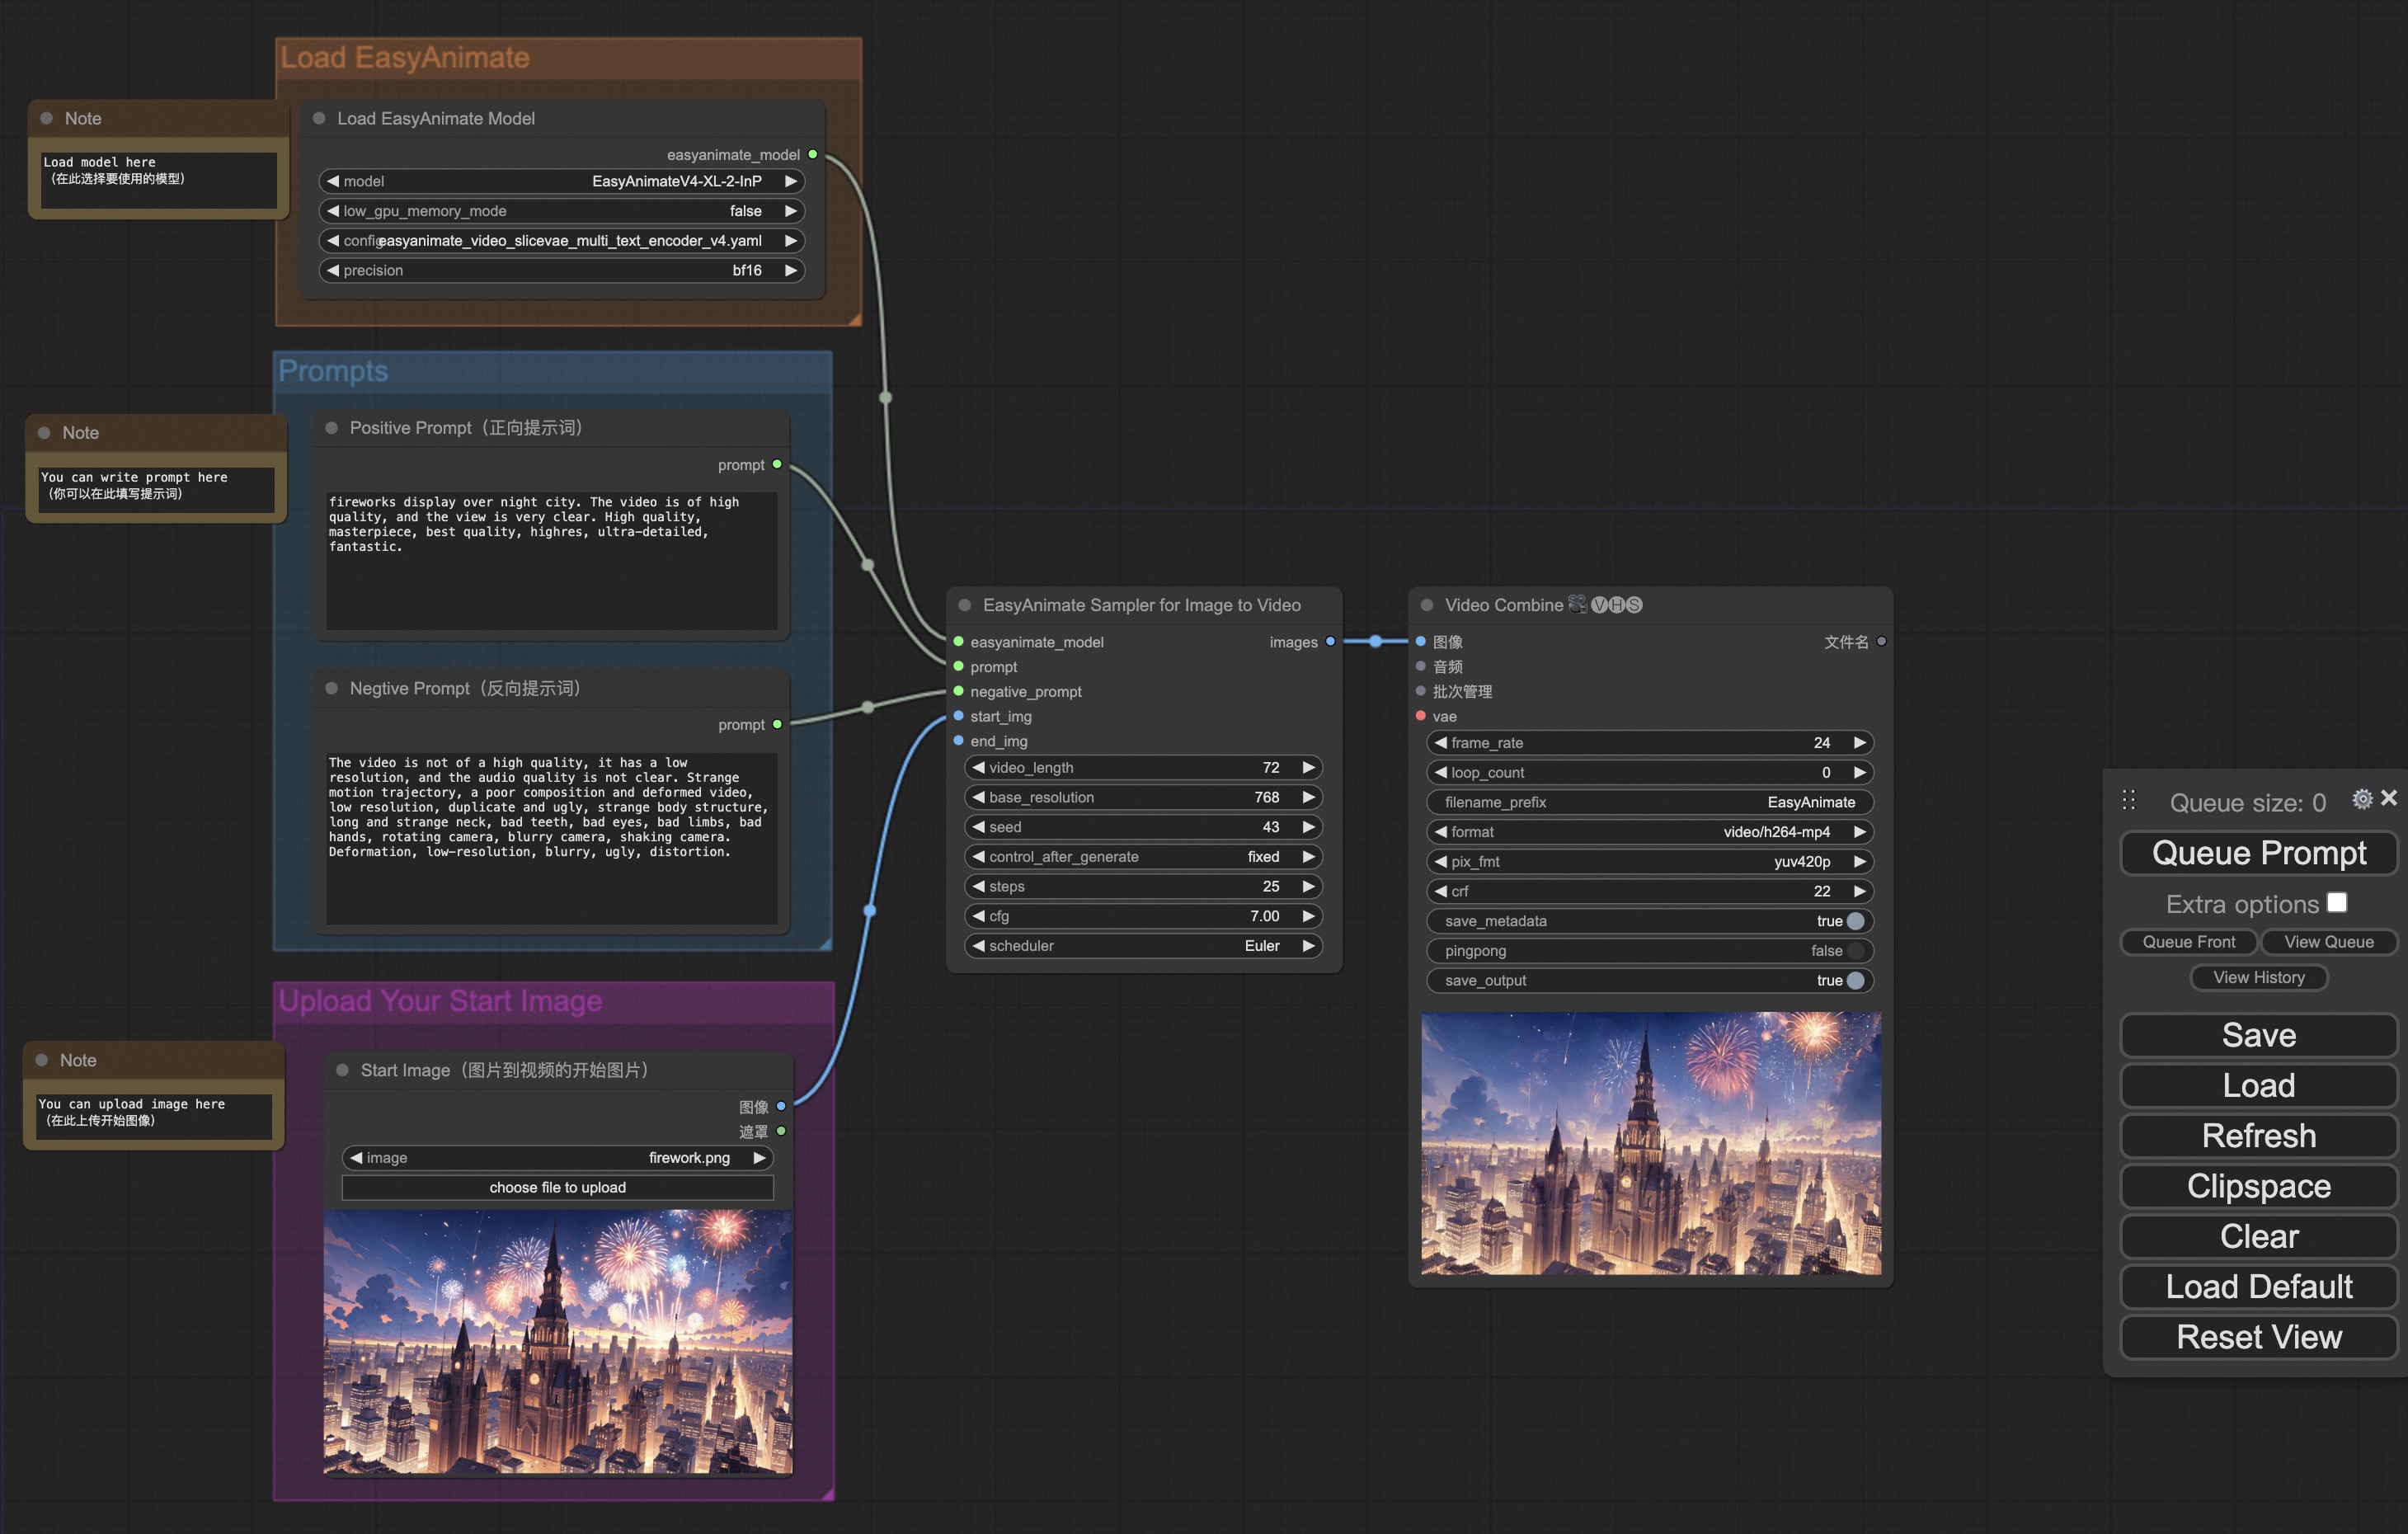
+
+You can run the demo using following photo:
+
+
+### Text to video generation
+Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/asset/v4/easyanimatev4_workflow_t2v.json) of the json:
+
+
+### Text to video generation With Lora
+We have provided a v4 version of the portrait Lora for testing, and the specific download link is [Lora download Link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/Personalized_Model/easyanimatev4_minimalism_lora.safetensors).
+
+You can put this Lora at ```ComfyUI/models/loras/easyanimate```.
+
+Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/asset/v4/easyanimatev4_workflow_lora.json) of the json:
+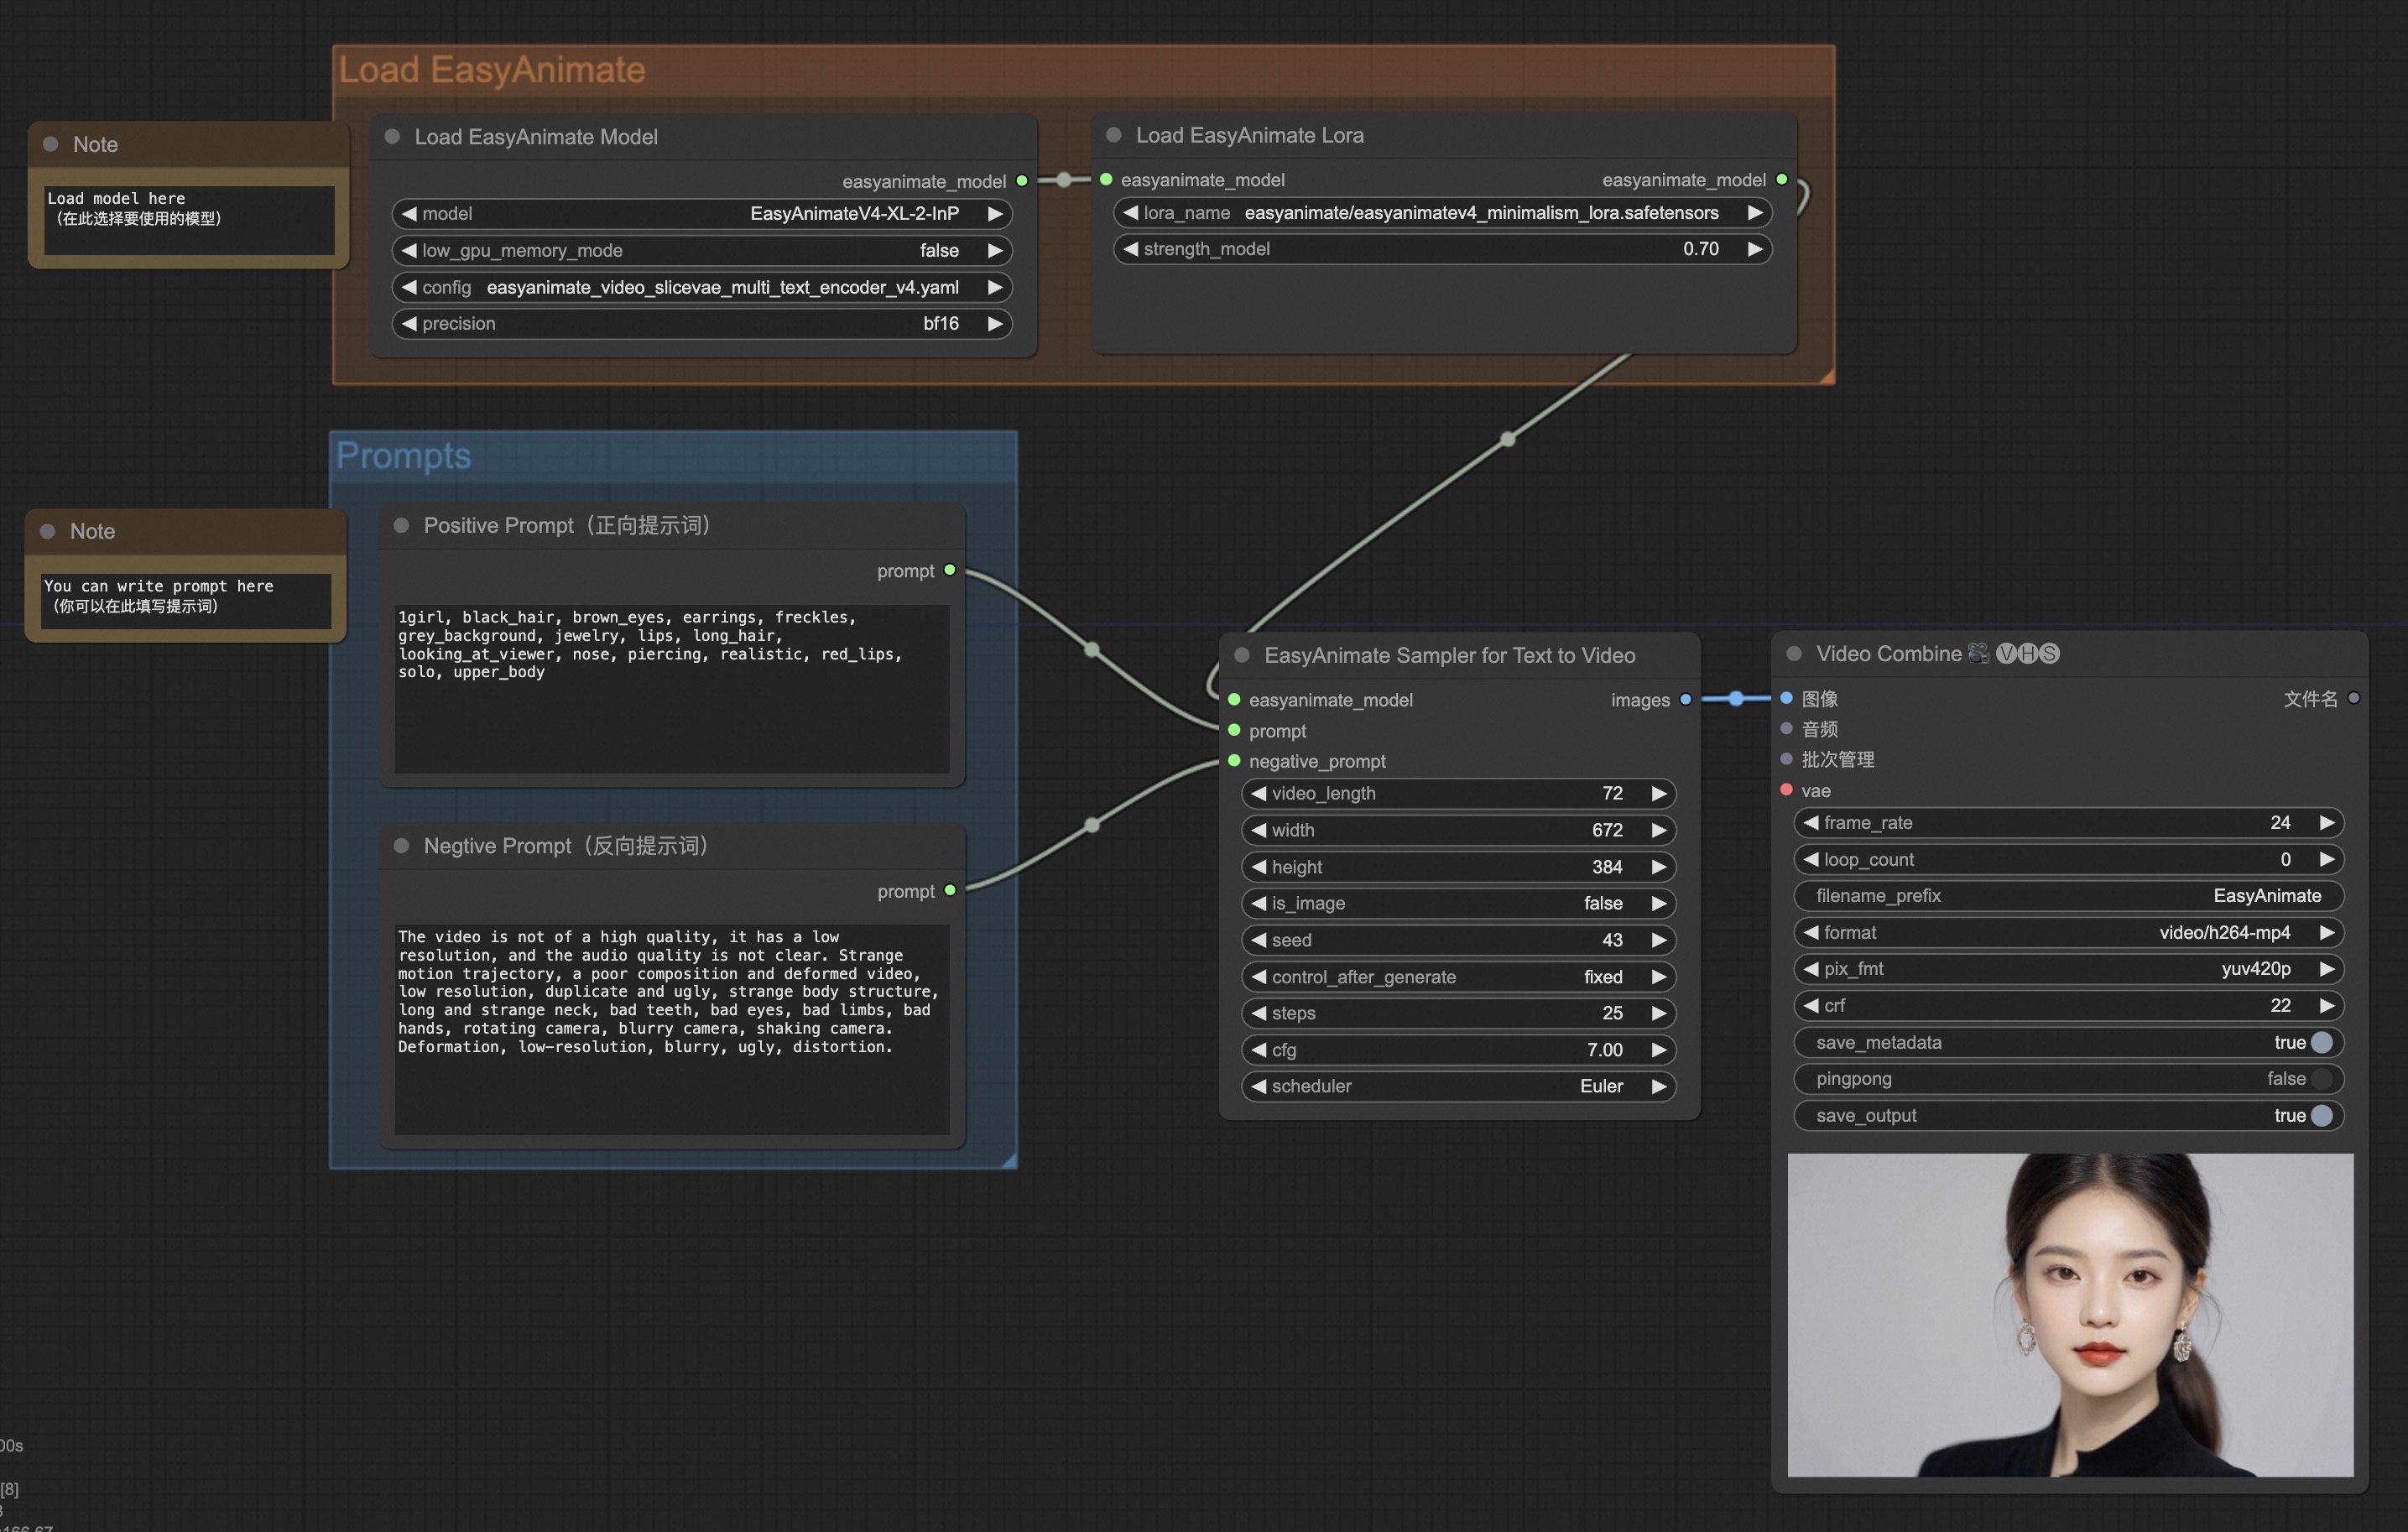
\ No newline at end of file
diff --git a/comfyui/comfyui_nodes.py b/comfyui/comfyui_nodes.py
new file mode 100644
index 0000000..faddf55
--- /dev/null
+++ b/comfyui/comfyui_nodes.py
@@ -0,0 +1,577 @@
+"""Modified from https://github.com/kijai/ComfyUI-EasyAnimateWrapper/blob/main/nodes.py
+"""
+import gc
+import json
+import os
+
+import comfy.model_management as mm
+import cv2
+import folder_paths
+import numpy as np
+import torch
+from comfy.utils import ProgressBar, load_torch_file
+from diffusers import (AutoencoderKL, CogVideoXDDIMScheduler, DDIMScheduler,
+ DPMSolverMultistepScheduler,
+ EulerAncestralDiscreteScheduler, EulerDiscreteScheduler,
+ PNDMScheduler)
+from einops import rearrange
+from omegaconf import OmegaConf
+from PIL import Image
+from transformers import T5EncoderModel, T5Tokenizer
+
+from ..cogvideox.data.bucket_sampler import ASPECT_RATIO_512, get_closest_ratio
+from ..cogvideox.models.autoencoder_magvit import AutoencoderKLCogVideoX
+from ..cogvideox.models.transformer3d import CogVideoXTransformer3DModel
+from ..cogvideox.pipeline.pipeline_cogvideox import CogVideoX_FUN_Pipeline
+from ..cogvideox.pipeline.pipeline_cogvideox_inpaint import (
+ CogVideoX_FUN_Pipeline_Inpaint)
+from ..cogvideox.utils.lora_utils import merge_lora, unmerge_lora
+from ..cogvideox.utils.utils import (get_image_to_video_latent,
+ get_video_to_video_latent,
+ save_videos_grid)
+
+# Compatible with Alibaba EAS for quick launch
+eas_cache_dir = '/stable-diffusion-cache/models'
+# The directory of the cogvideoxfun
+script_directory = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
+
+def tensor2pil(image):
+ return Image.fromarray(np.clip(255. * image.cpu().numpy(), 0, 255).astype(np.uint8))
+
+def numpy2pil(image):
+ return Image.fromarray(np.clip(255. * image, 0, 255).astype(np.uint8))
+
+def to_pil(image):
+ if isinstance(image, Image.Image):
+ return image
+ if isinstance(image, torch.Tensor):
+ return tensor2pil(image)
+ if isinstance(image, np.ndarray):
+ return numpy2pil(image)
+ raise ValueError(f"Cannot convert {type(image)} to PIL.Image")
+
+class LoadCogVideoX_FUN_Model:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "model": (
+ [
+ 'CogVideoX-Fun-2b-InP',
+ ],
+ {
+ "default": 'CogVideoX-Fun-2b-InP',
+ }
+ ),
+ "low_gpu_memory_mode":(
+ [False, True],
+ {
+ "default": False,
+ }
+ ),
+ "precision": (
+ ['fp16', 'bf16'],
+ {
+ "default": 'fp16'
+ }
+ ),
+
+ },
+ }
+
+ RETURN_TYPES = ("CogVideoXFUNSMODEL",)
+ RETURN_NAMES = ("cogvideoxfun_model",)
+ FUNCTION = "loadmodel"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def loadmodel(self, low_gpu_memory_mode, model, precision):
+ # Init weight_dtype and device
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+ weight_dtype = {"bf16": torch.bfloat16, "fp16": torch.float16, "fp32": torch.float32}[precision]
+
+ # Init processbar
+ pbar = ProgressBar(3)
+
+ # Detect model is existing or not
+ model_path = os.path.join(folder_paths.models_dir, "CogVideoX_FUN", model)
+
+ if not os.path.exists(model_path):
+ if os.path.exists(eas_cache_dir):
+ model_path = os.path.join(eas_cache_dir, 'CogVideoX_FUN', model)
+ else:
+ print(f"Please download cogvideoxfun model to: {model_path}")
+
+ vae = AutoencoderKLCogVideoX.from_pretrained(
+ model_path,
+ subfolder="vae",
+ ).to(weight_dtype)
+ # Update pbar
+ pbar.update(1)
+
+ # Load Sampler
+ print("Load Sampler.")
+ scheduler = EulerDiscreteScheduler.from_pretrained(model_path, subfolder='scheduler')
+ # Update pbar
+ pbar.update(1)
+
+ # Get Transformer
+ transformer = CogVideoXTransformer3DModel.from_pretrained_2d(
+ model_path,
+ subfolder="transformer",
+ ).to(weight_dtype)
+ # Update pbar
+ pbar.update(1)
+
+ # Get pipeline
+ if transformer.config.in_channels != vae.config.latent_channels:
+ pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
+ model_path,
+ vae=vae,
+ transformer=transformer,
+ scheduler=scheduler,
+ torch_dtype=weight_dtype
+ )
+ else:
+ pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
+ model_path,
+ vae=vae,
+ transformer=transformer,
+ scheduler=scheduler,
+ torch_dtype=weight_dtype
+ )
+ if low_gpu_memory_mode:
+ pipeline.enable_sequential_cpu_offload()
+ else:
+ pipeline.enable_model_cpu_offload()
+
+ cogvideoxfun_model = {
+ 'pipeline': pipeline,
+ 'dtype': weight_dtype,
+ 'model_path': model_path,
+ 'loras': [],
+ 'strength_model': [],
+ }
+ return (cogvideoxfun_model,)
+
+class LoadCogVideoX_FUN_Lora:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "cogvideoxfun_model": ("CogVideoXFUNSMODEL",),
+ "lora_name": (folder_paths.get_filename_list("loras"), {"default": None,}),
+ "strength_model": ("FLOAT", {"default": 1.0, "min": -100.0, "max": 100.0, "step": 0.01}),
+ }
+ }
+ RETURN_TYPES = ("CogVideoXFUNSMODEL",)
+ RETURN_NAMES = ("cogvideoxfun_model",)
+ FUNCTION = "load_lora"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def load_lora(self, cogvideoxfun_model, lora_name, strength_model):
+ if lora_name is not None:
+ return (
+ {
+ 'pipeline': cogvideoxfun_model["pipeline"],
+ 'dtype': cogvideoxfun_model["dtype"],
+ 'model_path': cogvideoxfun_model["model_path"],
+ 'loras': cogvideoxfun_model.get("loras", []) + [folder_paths.get_full_path("loras", lora_name)],
+ 'strength_model': cogvideoxfun_model.get("strength_model", []) + [strength_model],
+ },
+ )
+ else:
+ return (cogvideoxfun_model,)
+
+class TextBox:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "prompt": ("STRING", {"multiline": True, "default": "",}),
+ }
+ }
+
+ RETURN_TYPES = ("STRING_PROMPT",)
+ RETURN_NAMES =("prompt",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, prompt):
+ return (prompt, )
+
+class CogVideoX_FUN_I2VSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "cogvideoxfun_model": (
+ "CogVideoXFUNSMODEL",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 49, "min": 5, "max": 49, "step": 4}
+ ),
+ "base_resolution": (
+ [
+ 512,
+ 768,
+ 960,
+ 1024,
+ ], {"default": 768}
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 50, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 6.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Euler",
+ "Euler A",
+ "DPM++",
+ "PNDM",
+ "DDIM",
+ ],
+ {
+ "default": 'DDIM'
+ }
+ )
+ },
+ "optional":{
+ "start_img": ("IMAGE",),
+ "end_img": ("IMAGE",),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, cogvideoxfun_model, prompt, negative_prompt, video_length, base_resolution, seed, steps, cfg, scheduler, start_img=None, end_img=None):
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ start_img = [to_pil(_start_img) for _start_img in start_img] if start_img is not None else None
+ end_img = [to_pil(_end_img) for _end_img in end_img] if end_img is not None else None
+ # Count most suitable height and width
+ aspect_ratio_sample_size = {key : [x / 512 * base_resolution for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ original_width, original_height = start_img[0].size if type(start_img) is list else Image.open(start_img).size
+ closest_size, closest_ratio = get_closest_ratio(original_height, original_width, ratios=aspect_ratio_sample_size)
+ height, width = [int(x / 16) * 16 for x in closest_size]
+
+ # Get Pipeline
+ pipeline = cogvideoxfun_model['pipeline']
+ model_path = cogvideoxfun_model['model_path']
+
+ # Load Sampler
+ if scheduler == "DPM++":
+ noise_scheduler = DPMSolverMultistepScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ elif scheduler == "Euler":
+ noise_scheduler = EulerDiscreteScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ elif scheduler == "Euler A":
+ noise_scheduler = EulerAncestralDiscreteScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ elif scheduler == "PNDM":
+ noise_scheduler = PNDMScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ elif scheduler == "DDIM":
+ noise_scheduler = DDIMScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ pipeline.scheduler = noise_scheduler
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(start_img, end_img, video_length=video_length, sample_size=(height, width))
+
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight)
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight)
+ return (videos,)
+
+
+class CogVideoX_FUN_T2VSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "cogvideoxfun_model": (
+ "CogVideoXFUNSMODEL",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 49, "min": 5, "max": 49, "step": 4}
+ ),
+ "width": (
+ "INT", {"default": 1008, "min": 64, "max": 2048, "step": 16}
+ ),
+ "height": (
+ "INT", {"default": 576, "min": 64, "max": 2048, "step": 16}
+ ),
+ "is_image":(
+ [
+ False,
+ True
+ ],
+ {
+ "default": False,
+ }
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 50, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 6.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Euler",
+ "Euler A",
+ "DPM++",
+ "PNDM",
+ "DDIM",
+ ],
+ {
+ "default": 'DDIM'
+ }
+ ),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, cogvideoxfun_model, prompt, negative_prompt, video_length, width, height, is_image, seed, steps, cfg, scheduler):
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ # Get Pipeline
+ pipeline = cogvideoxfun_model['pipeline']
+ model_path = cogvideoxfun_model['model_path']
+
+ # Load Sampler
+ if scheduler == "DPM++":
+ noise_scheduler = DPMSolverMultistepScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ elif scheduler == "Euler":
+ noise_scheduler = EulerDiscreteScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ elif scheduler == "Euler A":
+ noise_scheduler = EulerAncestralDiscreteScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ elif scheduler == "PNDM":
+ noise_scheduler = PNDMScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ elif scheduler == "DDIM":
+ noise_scheduler = DDIMScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ pipeline.scheduler = noise_scheduler
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ video_length = 1 if is_image else video_length
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(None, None, video_length=video_length, sample_size=(height, width))
+
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight)
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight)
+ return (videos,)
+
+class CogVideoX_FUN_V2VSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "cogvideoxfun_model": (
+ "CogVideoXFUNSMODEL",
+ ),
+ "prompt": (
+ "STRING_PROMPT",
+ ),
+ "negative_prompt": (
+ "STRING_PROMPT",
+ ),
+ "video_length": (
+ "INT", {"default": 49, "min": 5, "max": 49, "step": 4}
+ ),
+ "base_resolution": (
+ [
+ 512,
+ 768,
+ 960,
+ 1024,
+ ], {"default": 768}
+ ),
+ "seed": (
+ "INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
+ ),
+ "steps": (
+ "INT", {"default": 50, "min": 1, "max": 200, "step": 1}
+ ),
+ "cfg": (
+ "FLOAT", {"default": 6.0, "min": 1.0, "max": 20.0, "step": 0.01}
+ ),
+ "denoise_strength": (
+ "FLOAT", {"default": 0.70, "min": 0.05, "max": 1.00, "step": 0.01}
+ ),
+ "scheduler": (
+ [
+ "Euler",
+ "Euler A",
+ "DPM++",
+ "PNDM",
+ "DDIM",
+ ],
+ {
+ "default": 'DDIM'
+ }
+ ),
+ "validation_video": ("IMAGE",),
+ }
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES =("images",)
+ FUNCTION = "process"
+ CATEGORY = "CogVideoXFUNWrapper"
+
+ def process(self, cogvideoxfun_model, prompt, negative_prompt, video_length, base_resolution, seed, steps, cfg, denoise_strength, scheduler, validation_video):
+ device = mm.get_torch_device()
+ offload_device = mm.unet_offload_device()
+
+ mm.soft_empty_cache()
+ gc.collect()
+
+ # Count most suitable height and width
+ aspect_ratio_sample_size = {key : [x / 512 * base_resolution for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ if type(validation_video) is str:
+ original_width, original_height = Image.fromarray(cv2.VideoCapture(validation_video).read()[1]).size
+ else:
+ validation_video = np.array(validation_video.cpu().numpy() * 255, np.uint8)
+ original_width, original_height = Image.fromarray(validation_video[0]).size
+ closest_size, closest_ratio = get_closest_ratio(original_height, original_width, ratios=aspect_ratio_sample_size)
+ height, width = [int(x / 16) * 16 for x in closest_size]
+
+ # Get Pipeline
+ pipeline = cogvideoxfun_model['pipeline']
+ model_path = cogvideoxfun_model['model_path']
+
+ # Load Sampler
+ if scheduler == "DPM++":
+ noise_scheduler = DPMSolverMultistepScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ elif scheduler == "Euler":
+ noise_scheduler = EulerDiscreteScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ elif scheduler == "Euler A":
+ noise_scheduler = EulerAncestralDiscreteScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ elif scheduler == "PNDM":
+ noise_scheduler = PNDMScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ elif scheduler == "DDIM":
+ noise_scheduler = DDIMScheduler.from_pretrained(model_path, subfolder= 'scheduler')
+ pipeline.scheduler = noise_scheduler
+
+ generator= torch.Generator(device).manual_seed(seed)
+
+ with torch.no_grad():
+ video_length = int((video_length - 1) // pipeline.vae.config.temporal_compression_ratio * pipeline.vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+ input_video, input_video_mask, clip_image = get_video_to_video_latent(validation_video, video_length=video_length, sample_size=(height, width))
+
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = merge_lora(pipeline, _lora_path, _lora_weight)
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = height,
+ width = width,
+ generator = generator,
+ guidance_scale = cfg,
+ num_inference_steps = steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ strength = float(denoise_strength),
+ comfyui_progressbar = True,
+ ).videos
+ videos = rearrange(sample, "b c t h w -> (b t) h w c")
+
+ for _lora_path, _lora_weight in zip(cogvideoxfun_model.get("loras", []), cogvideoxfun_model.get("strength_model", [])):
+ pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight)
+ return (videos,)
+
+NODE_CLASS_MAPPINGS = {
+ "TextBox": TextBox,
+ "LoadCogVideoX_FUN_Model": LoadCogVideoX_FUN_Model,
+ "LoadCogVideoX_FUN_Lora": LoadCogVideoX_FUN_Lora,
+ "CogVideoX_FUN_I2VSampler": CogVideoX_FUN_I2VSampler,
+ "CogVideoX_FUN_T2VSampler": CogVideoX_FUN_T2VSampler,
+ "CogVideoX_FUN_V2VSampler": CogVideoX_FUN_V2VSampler,
+}
+
+
+NODE_DISPLAY_NAME_MAPPINGS = {
+ "TextBox": "TextBox",
+ "LoadCogVideoX_FUN_Model": "Load CogVideoX-Fun Model",
+ "LoadCogVideoX_FUN_Lora": "Load CogVideoX-Fun Lora",
+ "CogVideoX_FUN_I2VSampler": "CogVideoX-Fun Sampler for Image to Video",
+ "CogVideoX_FUN_T2VSampler": "CogVideoX-Fun Sampler for Text to Video",
+ "CogVideoX_FUN_V2VSampler": "CogVideoX-Fun Sampler for Video to Video",
+}
\ No newline at end of file
diff --git a/comfyui/v1/cogvideoxfunv1_workflow_i2v.json b/comfyui/v1/cogvideoxfunv1_workflow_i2v.json
new file mode 100644
index 0000000..f59ba13
--- /dev/null
+++ b/comfyui/v1/cogvideoxfunv1_workflow_i2v.json
@@ -0,0 +1,450 @@
+{
+ "last_node_id": 83,
+ "last_link_id": 46,
+ "nodes": [
+ {
+ "id": 7,
+ "type": "LoadImage",
+ "pos": [
+ 258.76883544921907,
+ 468.15773315429715
+ ],
+ "size": [
+ 378.07147216796875,
+ 314.0000114440918
+ ],
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 45
+ ],
+ "shape": 3,
+ "label": "图像",
+ "slot_index": 0
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null,
+ "shape": 3,
+ "label": "遮罩"
+ }
+ ],
+ "title": "Start Image(图片到视频的开始图片)",
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "firework.png",
+ "image"
+ ]
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": [
+ 16,
+ 460
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload image here\n(在此上传开始图像)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ 20,
+ -300
+ ],
+ "size": {
+ "0": 210,
+ "1": 66.98204040527344
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Load model here\n(在此选择要使用的模型)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 83,
+ "type": "LoadCogVideoX_FUN_Model",
+ "pos": [
+ 300,
+ -294
+ ],
+ "size": {
+ "0": 315,
+ "1": 106
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "CogVideoXFUNSMODEL",
+ "links": [
+ 42
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoX_FUN_Model"
+ },
+ "widgets_values": [
+ "CogVideoX-Fun-2b-InP",
+ false,
+ "fp16"
+ ]
+ },
+ {
+ "id": 75,
+ "type": "TextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 43
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "TextBox"
+ },
+ "widgets_values": [
+ "fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 73,
+ "type": "TextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 44
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "TextBox"
+ },
+ "widgets_values": [
+ "The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion."
+ ]
+ },
+ {
+ "id": 82,
+ "type": "CogVideoX_FUN_I2VSampler",
+ "pos": [
+ 758,
+ 93
+ ],
+ "size": {
+ "0": 317.4000244140625,
+ "1": 282
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "CogVideoXFUNSMODEL",
+ "link": 42
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 43
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 44
+ },
+ {
+ "name": "start_img",
+ "type": "IMAGE",
+ "link": 45,
+ "slot_index": 3
+ },
+ {
+ "name": "end_img",
+ "type": "IMAGE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 46
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CogVideoX_FUN_I2VSampler"
+ },
+ "widgets_values": [
+ 49,
+ 512,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ "DDIM"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1134,
+ 93
+ ],
+ "size": [
+ 390.9534912109375,
+ 535.9734235491071
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 46,
+ "label": "图像",
+ "slot_index": 0
+ },
+ {
+ "name": "audio",
+ "type": "VHS_AUDIO",
+ "link": null,
+ "label": "音频"
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理"
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "shape": 3,
+ "label": "文件名",
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 8,
+ "loop_count": 0,
+ "filename_prefix": "CogVideoX-Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "EasyAnimate_00040.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 24
+ }
+ }
+ }
+ }
+ ],
+ "links": [
+ [
+ 42,
+ 83,
+ 0,
+ 82,
+ 0,
+ "CogVideoXFUNSMODEL"
+ ],
+ [
+ 43,
+ 75,
+ 0,
+ 82,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 44,
+ 73,
+ 0,
+ 82,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 45,
+ 7,
+ 0,
+ 82,
+ 3,
+ "IMAGE"
+ ],
+ [
+ 46,
+ 82,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24
+ },
+ {
+ "title": "Load CogVideoX-Fun",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24
+ },
+ {
+ "title": "Upload Your Start Image",
+ "bounding": [
+ 218,
+ 382,
+ 452,
+ 418
+ ],
+ "color": "#a1309b",
+ "font_size": 24
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.7513148009015778,
+ "offset": [
+ 265.8612156262443,
+ 436.6199667078462
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/comfyui/v1/cogvideoxfunv1_workflow_t2v.json b/comfyui/v1/cogvideoxfunv1_workflow_t2v.json
new file mode 100644
index 0000000..4b88e0e
--- /dev/null
+++ b/comfyui/v1/cogvideoxfunv1_workflow_t2v.json
@@ -0,0 +1,358 @@
+{
+ "last_node_id": 88,
+ "last_link_id": 52,
+ "nodes": [
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ 20,
+ -300
+ ],
+ "size": {
+ "0": 210,
+ "1": 66.98204040527344
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Load model here\n(在此选择要使用的模型)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 73,
+ "type": "TextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 51
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "TextBox"
+ },
+ "widgets_values": [
+ "The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion."
+ ]
+ },
+ {
+ "id": 87,
+ "type": "LoadCogVideoX_FUN_Model",
+ "pos": [
+ 302,
+ -285
+ ],
+ "size": {
+ "0": 315,
+ "1": 106
+ },
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "CogVideoXFUNSMODEL",
+ "links": [
+ 49
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoX_FUN_Model"
+ },
+ "widgets_values": [
+ "CogVideoX-Fun-2b-InP",
+ false,
+ "fp16"
+ ]
+ },
+ {
+ "id": 75,
+ "type": "TextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 50
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "TextBox"
+ },
+ "widgets_values": [
+ "A young woman with beautiful and clear eyes and blonde hair standing and white dress in a forest wearing a crown. She seems to be lost in thought, and the camera focuses on her face. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+ ]
+ },
+ {
+ "id": 88,
+ "type": "CogVideoX_FUN_T2VSampler",
+ "pos": [
+ 728,
+ -68
+ ],
+ "size": {
+ "0": 327.6000061035156,
+ "1": 290
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "CogVideoXFUNSMODEL",
+ "link": 49
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 50
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 51,
+ "slot_index": 2
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 52
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CogVideoX_FUN_T2VSampler"
+ },
+ "widgets_values": [
+ 49,
+ 672,
+ 384,
+ false,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ "DDIM"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1110,
+ -67
+ ],
+ "size": [
+ 390.9534912109375,
+ 535.9734235491071
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 52,
+ "label": "图像",
+ "slot_index": 0
+ },
+ {
+ "name": "audio",
+ "type": "VHS_AUDIO",
+ "link": null,
+ "label": "音频"
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理"
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "shape": 3,
+ "label": "文件名",
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 8,
+ "loop_count": 0,
+ "filename_prefix": "CogVideoX-Fun",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "EasyAnimate_00039.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 24
+ }
+ }
+ }
+ }
+ ],
+ "links": [
+ [
+ 49,
+ 87,
+ 0,
+ 88,
+ 0,
+ "CogVideoXFUNSMODEL"
+ ],
+ [
+ 50,
+ 75,
+ 0,
+ 88,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 51,
+ 73,
+ 0,
+ 88,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 52,
+ 88,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24
+ },
+ {
+ "title": "Load CogVideoX-Fun",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.8264462809917354,
+ "offset": [
+ 171.40912687862968,
+ 545.5627520384072
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/comfyui/v1/cogvideoxfunv1_workflow_v2v.json b/comfyui/v1/cogvideoxfunv1_workflow_v2v.json
new file mode 100644
index 0000000..a34c479
--- /dev/null
+++ b/comfyui/v1/cogvideoxfunv1_workflow_v2v.json
@@ -0,0 +1,488 @@
+{
+ "last_node_id": 88,
+ "last_link_id": 52,
+ "nodes": [
+ {
+ "id": 80,
+ "type": "Note",
+ "pos": [
+ 20,
+ -300
+ ],
+ "size": {
+ "0": 210,
+ "1": 66.98204040527344
+ },
+ "flags": {},
+ "order": 0,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "Load model here\n(在此选择要使用的模型)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 78,
+ "type": "Note",
+ "pos": [
+ 18,
+ -46
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 1,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can write prompt here\n(你可以在此填写提示词)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 79,
+ "type": "Note",
+ "pos": [
+ 15.739953613281248,
+ 462.38664912015946
+ ],
+ "size": {
+ "0": 210,
+ "1": 58
+ },
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "properties": {
+ "text": ""
+ },
+ "widgets_values": [
+ "You can upload video here\n(在此上传视频)"
+ ],
+ "color": "#432",
+ "bgcolor": "#653"
+ },
+ {
+ "id": 85,
+ "type": "VHS_LoadVideo",
+ "pos": [
+ 336,
+ 470
+ ],
+ "size": [
+ 235.1999969482422,
+ 398.971426827567
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 49
+ ],
+ "shape": 3,
+ "slot_index": 0
+ },
+ {
+ "name": "frame_count",
+ "type": "INT",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "links": null,
+ "shape": 3
+ },
+ {
+ "name": "video_info",
+ "type": "VHS_VIDEOINFO",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_LoadVideo"
+ },
+ "widgets_values": {
+ "video": "00000125.mp4",
+ "force_rate": 0,
+ "force_size": "Disabled",
+ "custom_width": 512,
+ "custom_height": 512,
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "select_every_nth": 1,
+ "choose video to upload": "image",
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "frame_load_cap": 0,
+ "skip_first_frames": 0,
+ "force_rate": 0,
+ "filename": "00000125.mp4",
+ "type": "input",
+ "format": "video/mp4",
+ "select_every_nth": 1
+ }
+ }
+ }
+ },
+ {
+ "id": 73,
+ "type": "TextBox",
+ "pos": [
+ 250,
+ 160
+ ],
+ "size": {
+ "0": 383.7149963378906,
+ "1": 183.83506774902344
+ },
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 50
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Negtive Prompt(反向提示词)",
+ "properties": {
+ "Node name for S&R": "TextBox"
+ },
+ "widgets_values": [
+ "The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion."
+ ]
+ },
+ {
+ "id": 88,
+ "type": "LoadCogVideoX_FUN_Model",
+ "pos": [
+ 309,
+ -286
+ ],
+ "size": {
+ "0": 315,
+ "1": 106
+ },
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "CogVideoXFUNSMODEL",
+ "links": [
+ 52
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadCogVideoX_FUN_Model"
+ },
+ "widgets_values": [
+ "CogVideoX-Fun-2b-InP",
+ false,
+ "fp16"
+ ]
+ },
+ {
+ "id": 75,
+ "type": "TextBox",
+ "pos": [
+ 250,
+ -50
+ ],
+ "size": {
+ "0": 383.54010009765625,
+ "1": 156.71620178222656
+ },
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "outputs": [
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "links": [
+ 51
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "title": "Positive Prompt(正向提示词)",
+ "properties": {
+ "Node name for S&R": "TextBox"
+ },
+ "widgets_values": [
+ "A beautiful woman is playing the guitar. The video quality is high and the picture is clear. High quality, masterpiece, the best quality, high resolution, ultra careful."
+ ]
+ },
+ {
+ "id": 87,
+ "type": "CogVideoX_FUN_V2VSampler",
+ "pos": [
+ 778,
+ 93
+ ],
+ "size": {
+ "0": 317.4000244140625,
+ "1": 286
+ },
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "cogvideoxfun_model",
+ "type": "CogVideoXFUNSMODEL",
+ "link": 52
+ },
+ {
+ "name": "prompt",
+ "type": "STRING_PROMPT",
+ "link": 51,
+ "slot_index": 1
+ },
+ {
+ "name": "negative_prompt",
+ "type": "STRING_PROMPT",
+ "link": 50
+ },
+ {
+ "name": "validation_video",
+ "type": "IMAGE",
+ "link": 49,
+ "slot_index": 3
+ }
+ ],
+ "outputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "links": [
+ 48
+ ],
+ "shape": 3,
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CogVideoX_FUN_V2VSampler"
+ },
+ "widgets_values": [
+ 49,
+ 512,
+ 43,
+ "fixed",
+ 50,
+ 6,
+ 0.7,
+ "DDIM"
+ ]
+ },
+ {
+ "id": 17,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 1134,
+ 93
+ ],
+ "size": [
+ 390.9534912109375,
+ 535.9734235491071
+ ],
+ "flags": {},
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 48,
+ "label": "图像",
+ "slot_index": 0
+ },
+ {
+ "name": "audio",
+ "type": "VHS_AUDIO",
+ "link": null,
+ "label": "音频"
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "label": "批次管理"
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null,
+ "shape": 3,
+ "label": "文件名",
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine"
+ },
+ "widgets_values": {
+ "frame_rate": 8,
+ "loop_count": 0,
+ "filename_prefix": "EasyAnimate",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 22,
+ "save_metadata": true,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "EasyAnimate_00042.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 8
+ }
+ }
+ }
+ }
+ ],
+ "links": [
+ [
+ 48,
+ 87,
+ 0,
+ 17,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 49,
+ 85,
+ 0,
+ 87,
+ 3,
+ "IMAGE"
+ ],
+ [
+ 50,
+ 73,
+ 0,
+ 87,
+ 2,
+ "STRING_PROMPT"
+ ],
+ [
+ 51,
+ 75,
+ 0,
+ 87,
+ 1,
+ "STRING_PROMPT"
+ ],
+ [
+ 52,
+ 88,
+ 0,
+ 87,
+ 0,
+ "CogVideoXFUNSMODEL"
+ ]
+ ],
+ "groups": [
+ {
+ "title": "Prompts",
+ "bounding": [
+ 218,
+ -127,
+ 450,
+ 483
+ ],
+ "color": "#3f789e",
+ "font_size": 24
+ },
+ {
+ "title": "Load CogVideoX-Fun",
+ "bounding": [
+ 220,
+ -380,
+ 472,
+ 232
+ ],
+ "color": "#b06634",
+ "font_size": 24
+ },
+ {
+ "title": "Upload Your Video",
+ "bounding": [
+ 218,
+ 385,
+ 456,
+ 498
+ ],
+ "color": "#a1309b",
+ "font_size": 24
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 0.683013455365071,
+ "offset": [
+ 322.5575500900931,
+ 444.05399028364593
+ ]
+ },
+ "workspace_info": {
+ "id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
+ }
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/config/zero_stage2_config.json b/config/zero_stage2_config.json
new file mode 100644
index 0000000..e60ea05
--- /dev/null
+++ b/config/zero_stage2_config.json
@@ -0,0 +1,16 @@
+{
+ "bf16": {
+ "enabled": true
+ },
+ "train_micro_batch_size_per_gpu": 1,
+ "train_batch_size": "auto",
+ "gradient_accumulation_steps": "auto",
+ "dump_state": true,
+ "zero_optimization": {
+ "stage": 2,
+ "overlap_comm": true,
+ "contiguous_gradients": true,
+ "sub_group_size": 1e9,
+ "reduce_bucket_size": 5e8
+ }
+}
\ No newline at end of file
diff --git a/datasets/put datasets here.txt b/datasets/put datasets here.txt
new file mode 100644
index 0000000..e69de29
diff --git a/models/put models here.txt b/models/put models here.txt
new file mode 100644
index 0000000..e69de29
diff --git a/predict_i2v.py b/predict_i2v.py
new file mode 100644
index 0000000..e8b6319
--- /dev/null
+++ b/predict_i2v.py
@@ -0,0 +1,238 @@
+
+
+import json
+import os
+
+import numpy as np
+import torch
+from diffusers import (AutoencoderKL, CogVideoXDDIMScheduler, DDIMScheduler,
+ DPMSolverMultistepScheduler,
+ EulerAncestralDiscreteScheduler, EulerDiscreteScheduler,
+ PNDMScheduler)
+from transformers import T5EncoderModel, T5Tokenizer
+from omegaconf import OmegaConf
+from PIL import Image
+
+from cogvideox.models.transformer3d import CogVideoXTransformer3DModel
+from cogvideox.models.autoencoder_magvit import AutoencoderKLCogVideoX
+from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_FUN_Pipeline
+from cogvideox.pipeline.pipeline_cogvideox_inpaint import CogVideoX_FUN_Pipeline_Inpaint
+from cogvideox.utils.lora_utils import merge_lora, unmerge_lora
+from cogvideox.utils.utils import get_image_to_video_latent, save_videos_grid
+
+# Low gpu memory mode, this is used when the GPU memory is under 16GB
+low_gpu_memory_mode = False
+
+# Config and model path
+model_name = "models/Diffusion_Transformer/CogVideoX-Fun-2b-InP"
+
+# Choose the sampler in "Euler" "Euler A" "DPM++" "PNDM" "DDIM_Cog" and "DDIM_Origin"
+sampler_name = "DDIM_Origin"
+
+# Load pretrained model if need
+transformer_path = None
+vae_path = None
+lora_path = None
+
+# Other params
+sample_size = [384, 672]
+video_length = 49
+fps = 8
+
+# If you want to generate ultra long videos, please set partial_video_length as the length of each sub video segment
+partial_video_length = None
+overlap_video_length = 4
+
+# Use torch.float16 if GPU does not support torch.bfloat16
+# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
+weight_dtype = torch.bfloat16
+# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
+validation_image_start = "asset/1.png"
+validation_image_end = None
+
+# prompts
+prompt = "A dog is shaking head. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+negative_prompt = "The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion. "
+guidance_scale = 6.0
+seed = 43
+num_inference_steps = 25
+lora_weight = 0.55
+save_path = "samples/cogvideox-fun-videos_i2v"
+
+transformer = CogVideoXTransformer3DModel.from_pretrained_2d(
+ model_name,
+ subfolder="transformer",
+).to(weight_dtype)
+
+if transformer_path is not None:
+ print(f"From checkpoint: {transformer_path}")
+ if transformer_path.endswith("safetensors"):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(transformer_path)
+ else:
+ state_dict = torch.load(transformer_path, map_location="cpu")
+ state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
+
+ m, u = transformer.load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+
+# Get Vae
+vae = AutoencoderKLCogVideoX.from_pretrained(
+ model_name,
+ subfolder="vae"
+).to(weight_dtype)
+
+if vae_path is not None:
+ print(f"From checkpoint: {vae_path}")
+ if vae_path.endswith("safetensors"):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(vae_path)
+ else:
+ state_dict = torch.load(vae_path, map_location="cpu")
+ state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
+
+ m, u = vae.load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+
+text_encoder = T5EncoderModel.from_pretrained(
+ model_name, subfolder="text_encoder", torch_dtype=weight_dtype
+)
+# Get Scheduler
+Choosen_Scheduler = scheduler_dict = {
+ "Euler": EulerDiscreteScheduler,
+ "Euler A": EulerAncestralDiscreteScheduler,
+ "DPM++": DPMSolverMultistepScheduler,
+ "PNDM": PNDMScheduler,
+ "DDIM_Cog": CogVideoXDDIMScheduler,
+ "DDIM_Origin": DDIMScheduler,
+}[sampler_name]
+scheduler = Choosen_Scheduler.from_pretrained(
+ model_name,
+ subfolder="scheduler"
+)
+
+if transformer.config.in_channels != vae.config.latent_channels:
+ pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
+ model_name,
+ vae=vae,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ scheduler=scheduler,
+ torch_dtype=weight_dtype
+ )
+else:
+ pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
+ model_name,
+ vae=vae,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ scheduler=scheduler,
+ torch_dtype=weight_dtype
+ )
+if low_gpu_memory_mode:
+ pipeline.enable_sequential_cpu_offload()
+else:
+ pipeline.enable_model_cpu_offload()
+
+generator = torch.Generator(device="cuda").manual_seed(seed)
+
+if lora_path is not None:
+ pipeline = merge_lora(pipeline, lora_path, lora_weight)
+
+if partial_video_length is not None:
+ init_frames = 0
+ last_frames = init_frames + partial_video_length
+ while init_frames < video_length:
+ if last_frames >= video_length:
+ if pipeline.vae.quant_conv.weight.ndim==5:
+ mini_batch_encoder = 4
+ _partial_video_length = video_length - init_frames
+ _partial_video_length = int((_partial_video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1
+ else:
+ _partial_video_length = video_length - init_frames
+
+ if _partial_video_length <= 0:
+ break
+ else:
+ _partial_video_length = partial_video_length
+
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(validation_image, None, video_length=_partial_video_length, sample_size=sample_size)
+
+ with torch.no_grad():
+ sample = pipeline(
+ prompt + ". The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic. ",
+ num_frames = _partial_video_length,
+ negative_prompt = negative_prompt,
+ height = sample_size[0],
+ width = sample_size[1],
+ generator = generator,
+ guidance_scale = guidance_scale,
+ num_inference_steps = num_inference_steps,
+
+ video = input_video,
+ mask_video = input_video_mask
+ ).videos
+
+ if init_frames != 0:
+ mix_ratio = torch.from_numpy(
+ np.array([float(_index) / float(overlap_video_length) for _index in range(overlap_video_length)], np.float32)
+ ).unsqueeze(0).unsqueeze(0).unsqueeze(-1).unsqueeze(-1)
+
+ new_sample[:, :, -overlap_video_length:] = new_sample[:, :, -overlap_video_length:] * (1 - mix_ratio) + \
+ sample[:, :, :overlap_video_length] * mix_ratio
+ new_sample = torch.cat([new_sample, sample[:, :, overlap_video_length:]], dim = 2)
+
+ sample = new_sample
+ else:
+ new_sample = sample
+
+ if last_frames >= video_length:
+ break
+
+ validation_image = [
+ Image.fromarray(
+ (sample[0, :, _index].transpose(0, 1).transpose(1, 2) * 255).numpy().astype(np.uint8)
+ ) for _index in range(-overlap_video_length, 0)
+ ]
+
+ init_frames = init_frames + _partial_video_length - overlap_video_length
+ last_frames = init_frames + _partial_video_length
+else:
+ video_length = int((video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(validation_image_start, validation_image_end, video_length=video_length, sample_size=sample_size)
+
+ with torch.no_grad():
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = sample_size[0],
+ width = sample_size[1],
+ generator = generator,
+ guidance_scale = guidance_scale,
+ num_inference_steps = num_inference_steps,
+
+ video = input_video,
+ mask_video = input_video_mask
+ ).videos
+
+if lora_path is not None:
+ pipeline = unmerge_lora(pipeline, lora_path, lora_weight)
+
+if not os.path.exists(save_path):
+ os.makedirs(save_path, exist_ok=True)
+
+index = len([path for path in os.listdir(save_path)]) + 1
+prefix = str(index).zfill(8)
+
+if video_length == 1:
+ video_path = os.path.join(save_path, prefix + ".png")
+
+ image = sample[0, :, 0]
+ image = image.transpose(0, 1).transpose(1, 2)
+ image = (image * 255).numpy().astype(np.uint8)
+ image = Image.fromarray(image)
+ image.save(video_path)
+else:
+ video_path = os.path.join(save_path, prefix + ".mp4")
+ save_videos_grid(sample, video_path, fps=fps)
\ No newline at end of file
diff --git a/predict_t2v.py b/predict_t2v.py
new file mode 100644
index 0000000..f0e250b
--- /dev/null
+++ b/predict_t2v.py
@@ -0,0 +1,182 @@
+
+
+import json
+import os
+
+import numpy as np
+import torch
+from diffusers import (AutoencoderKL, CogVideoXDDIMScheduler, DDIMScheduler,
+ DPMSolverMultistepScheduler,
+ EulerAncestralDiscreteScheduler, EulerDiscreteScheduler,
+ PNDMScheduler)
+from transformers import T5EncoderModel, T5Tokenizer
+from omegaconf import OmegaConf
+from PIL import Image
+
+from cogvideox.models.transformer3d import CogVideoXTransformer3DModel
+from cogvideox.models.autoencoder_magvit import AutoencoderKLCogVideoX
+from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_FUN_Pipeline
+from cogvideox.pipeline.pipeline_cogvideox_inpaint import CogVideoX_FUN_Pipeline_Inpaint
+from cogvideox.utils.lora_utils import merge_lora, unmerge_lora
+from cogvideox.utils.utils import get_image_to_video_latent, save_videos_grid
+
+# Low gpu memory mode, this is used when the GPU memory is under 16GB
+low_gpu_memory_mode = False
+
+# model path
+model_name = "models/Diffusion_Transformer/CogVideoX-Fun-2b-InP"
+
+# Choose the sampler in "Euler" "Euler A" "DPM++" "PNDM" and "DDIM"
+sampler_name = "DDIM_Origin"
+
+# Load pretrained model if need
+transformer_path = None
+vae_path = None
+lora_path = None
+
+# Other params
+sample_size = [384, 672]
+video_length = 49
+fps = 8
+
+# Use torch.float16 if GPU does not support torch.bfloat16
+# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
+weight_dtype = torch.bfloat16
+prompt = "A dog is shaking head. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+negative_prompt = "The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion. "
+guidance_scale = 6.0
+seed = 43
+num_inference_steps = 25
+lora_weight = 0.55
+save_path = "samples/cogvideox-fun-videos-t2v"
+
+transformer = CogVideoXTransformer3DModel.from_pretrained_2d(
+ model_name,
+ subfolder="transformer",
+).to(weight_dtype)
+
+if transformer_path is not None:
+ print(f"From checkpoint: {transformer_path}")
+ if transformer_path.endswith("safetensors"):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(transformer_path)
+ else:
+ state_dict = torch.load(transformer_path, map_location="cpu")
+ state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
+
+ m, u = transformer.load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+
+# Get Vae
+vae = AutoencoderKLCogVideoX.from_pretrained(
+ model_name,
+ subfolder="vae"
+).to(weight_dtype)
+
+if vae_path is not None:
+ print(f"From checkpoint: {vae_path}")
+ if vae_path.endswith("safetensors"):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(vae_path)
+ else:
+ state_dict = torch.load(vae_path, map_location="cpu")
+ state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
+
+ m, u = vae.load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+
+text_encoder = T5EncoderModel.from_pretrained(
+ model_name, subfolder="text_encoder", torch_dtype=weight_dtype
+)
+# Get Scheduler
+Choosen_Scheduler = scheduler_dict = {
+ "Euler": EulerDiscreteScheduler,
+ "Euler A": EulerAncestralDiscreteScheduler,
+ "DPM++": DPMSolverMultistepScheduler,
+ "PNDM": PNDMScheduler,
+ "DDIM_Cog": CogVideoXDDIMScheduler,
+ "DDIM_Origin": DDIMScheduler,
+}[sampler_name]
+scheduler = Choosen_Scheduler.from_pretrained(
+ model_name,
+ subfolder="scheduler"
+)
+
+if transformer.config.in_channels != vae.config.latent_channels:
+ pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
+ model_name,
+ vae=vae,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ scheduler=scheduler,
+ torch_dtype=weight_dtype
+ )
+else:
+ pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
+ model_name,
+ vae=vae,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ scheduler=scheduler,
+ torch_dtype=weight_dtype
+ )
+if low_gpu_memory_mode:
+ pipeline.enable_sequential_cpu_offload()
+else:
+ pipeline.enable_model_cpu_offload()
+
+generator = torch.Generator(device="cuda").manual_seed(seed)
+
+if lora_path is not None:
+ pipeline = merge_lora(pipeline, lora_path, lora_weight)
+
+with torch.no_grad():
+ video_length = int((video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+ if transformer.config.in_channels != vae.config.latent_channels:
+ input_video, input_video_mask, _ = get_image_to_video_latent(None, None, video_length=video_length, sample_size=sample_size)
+
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = sample_size[0],
+ width = sample_size[1],
+ generator = generator,
+ guidance_scale = guidance_scale,
+ num_inference_steps = num_inference_steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ ).videos
+ else:
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = sample_size[0],
+ width = sample_size[1],
+ generator = generator,
+ guidance_scale = guidance_scale,
+ num_inference_steps = num_inference_steps,
+ ).videos
+
+if lora_path is not None:
+ pipeline = unmerge_lora(pipeline, lora_path, lora_weight)
+
+if not os.path.exists(save_path):
+ os.makedirs(save_path, exist_ok=True)
+
+index = len([path for path in os.listdir(save_path)]) + 1
+prefix = str(index).zfill(8)
+
+if video_length == 1:
+ video_path = os.path.join(save_path, prefix + ".png")
+
+ image = sample[0, :, 0]
+ image = image.transpose(0, 1).transpose(1, 2)
+ image = (image * 255).numpy().astype(np.uint8)
+ image = Image.fromarray(image)
+ image.save(video_path)
+else:
+ video_path = os.path.join(save_path, prefix + ".mp4")
+ save_videos_grid(sample, video_path, fps=fps)
\ No newline at end of file
diff --git a/predict_v2v.py b/predict_v2v.py
new file mode 100644
index 0000000..fc1c657
--- /dev/null
+++ b/predict_v2v.py
@@ -0,0 +1,177 @@
+import json
+import os
+
+import cv2
+import numpy as np
+import torch
+from diffusers import (AutoencoderKL, CogVideoXDDIMScheduler, DDIMScheduler,
+ DPMSolverMultistepScheduler,
+ EulerAncestralDiscreteScheduler, EulerDiscreteScheduler,
+ PNDMScheduler)
+from omegaconf import OmegaConf
+from PIL import Image
+from transformers import (CLIPImageProcessor, CLIPVisionModelWithProjection,
+ T5EncoderModel, T5Tokenizer)
+
+from cogvideox.models.autoencoder_magvit import AutoencoderKLCogVideoX
+from cogvideox.models.transformer3d import CogVideoXTransformer3DModel
+from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_FUN_Pipeline
+from cogvideox.pipeline.pipeline_cogvideox_inpaint import \
+ CogVideoX_FUN_Pipeline_Inpaint
+from cogvideox.utils.lora_utils import merge_lora, unmerge_lora
+from cogvideox.utils.utils import get_video_to_video_latent, save_videos_grid
+
+# Low gpu memory mode, this is used when the GPU memory is under 16GB
+low_gpu_memory_mode = False
+
+# model path
+model_name = "models/Diffusion_Transformer/CogVideoX-Fun-2b-InP"
+
+# Choose the sampler in "Euler" "Euler A" "DPM++" "PNDM" and "DDIM"
+sampler_name = "DDIM_Origin"
+
+# Load pretrained model if need
+transformer_path = None
+vae_path = None
+lora_path = None
+# Other params
+sample_size = [384, 672]
+video_length = 49
+fps = 8
+
+# Use torch.float16 if GPU does not support torch.bfloat16
+# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
+weight_dtype = torch.bfloat16
+# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
+validation_video = "asset/03480_03600_good_scenes.mp4"
+denoise_strength = 0.70
+
+# prompts
+prompt = "A dog is shaking head. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
+negative_prompt = "The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion. "
+guidance_scale = 6.0
+seed = 43
+num_inference_steps = 25
+lora_weight = 0.55
+save_path = "samples/cogvideox-fun-videos_v2v"
+
+transformer = CogVideoXTransformer3DModel.from_pretrained_2d(
+ model_name,
+ subfolder="transformer",
+).to(weight_dtype)
+
+if transformer_path is not None:
+ print(f"From checkpoint: {transformer_path}")
+ if transformer_path.endswith("safetensors"):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(transformer_path)
+ else:
+ state_dict = torch.load(transformer_path, map_location="cpu")
+ state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
+
+ m, u = transformer.load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+
+# Get Vae
+vae = AutoencoderKLCogVideoX.from_pretrained(
+ model_name,
+ subfolder="vae"
+).to(weight_dtype)
+
+if vae_path is not None:
+ print(f"From checkpoint: {vae_path}")
+ if vae_path.endswith("safetensors"):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(vae_path)
+ else:
+ state_dict = torch.load(vae_path, map_location="cpu")
+ state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
+
+ m, u = vae.load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+
+text_encoder = T5EncoderModel.from_pretrained(
+ model_name, subfolder="text_encoder", torch_dtype=weight_dtype
+)
+# Get Scheduler
+Choosen_Scheduler = scheduler_dict = {
+ "Euler": EulerDiscreteScheduler,
+ "Euler A": EulerAncestralDiscreteScheduler,
+ "DPM++": DPMSolverMultistepScheduler,
+ "PNDM": PNDMScheduler,
+ "DDIM_Cog": CogVideoXDDIMScheduler,
+ "DDIM_Origin": DDIMScheduler,
+}[sampler_name]
+scheduler = Choosen_Scheduler.from_pretrained(
+ model_name,
+ subfolder="scheduler"
+)
+
+if transformer.config.in_channels != vae.config.latent_channels:
+ pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
+ model_name,
+ vae=vae,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ scheduler=scheduler,
+ torch_dtype=weight_dtype
+ )
+else:
+ pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
+ model_name,
+ vae=vae,
+ text_encoder=text_encoder,
+ transformer=transformer,
+ scheduler=scheduler,
+ torch_dtype=weight_dtype
+ )
+
+if low_gpu_memory_mode:
+ pipeline.enable_sequential_cpu_offload()
+else:
+ pipeline.enable_model_cpu_offload()
+
+generator = torch.Generator(device="cuda").manual_seed(seed)
+
+if lora_path is not None:
+ pipeline = merge_lora(pipeline, lora_path, lora_weight, "cuda")
+
+video_length = int((video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
+input_video, input_video_mask, clip_image = get_video_to_video_latent(validation_video, video_length=video_length, sample_size=sample_size)
+
+with torch.no_grad():
+ sample = pipeline(
+ prompt,
+ num_frames = video_length,
+ negative_prompt = negative_prompt,
+ height = sample_size[0],
+ width = sample_size[1],
+ generator = generator,
+ guidance_scale = guidance_scale,
+ num_inference_steps = num_inference_steps,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ strength = denoise_strength,
+ ).videos
+
+if lora_path is not None:
+ pipeline = unmerge_lora(pipeline, lora_path, lora_weight, "cuda")
+
+if not os.path.exists(save_path):
+ os.makedirs(save_path, exist_ok=True)
+
+index = len([path for path in os.listdir(save_path)]) + 1
+prefix = str(index).zfill(8)
+
+if video_length == 1:
+ save_sample_path = os.path.join(save_path, prefix + f".png")
+
+ image = sample[0, :, 0]
+ image = image.transpose(0, 1).transpose(1, 2)
+ image = (image * 255).numpy().astype(np.uint8)
+ image = Image.fromarray(image)
+ image.save(save_sample_path)
+else:
+ video_path = os.path.join(save_path, prefix + ".mp4")
+ save_videos_grid(sample, video_path, fps=fps)
\ No newline at end of file
diff --git a/requirements.txt b/requirements.txt
new file mode 100644
index 0000000..a81f6bc
--- /dev/null
+++ b/requirements.txt
@@ -0,0 +1,28 @@
+Pillow
+einops
+safetensors
+timm
+tomesd
+torch>=2.1.2
+torchdiffeq
+torchsde
+xformers
+decord
+datasets
+numpy
+scikit-image
+opencv-python
+omegaconf
+SentencePiece
+albumentations
+imageio[ffmpeg]
+imageio[pyav]
+tensorboard
+beautifulsoup4
+ftfy
+func_timeout
+deepspeed
+accelerate>=0.25.0
+gradio>=3.41.2
+diffusers>=0.28.2
+transformers>=4.37.2
diff --git a/scripts/README_TRAIN.md b/scripts/README_TRAIN.md
new file mode 100644
index 0000000..5e33cb7
--- /dev/null
+++ b/scripts/README_TRAIN.md
@@ -0,0 +1,101 @@
+## Training Code
+
+The default training commands for the different versions are as follows:
+
+We can choose whether to use deep speed in CogVideoX-Arbitrary, which can save a lot of video memory.
+
+CogVideoX-Arbitrary without deepspeed:
+```sh
+export MODEL_NAME="models/Diffusion_Transformer/CogVideoX-Fun-2b-InP"
+export DATASET_NAME="datasets/internal_datasets/"
+export DATASET_META_NAME="datasets/internal_datasets/metadata.json"
+export NCCL_IB_DISABLE=1
+export NCCL_P2P_DISABLE=1
+NCCL_DEBUG=INFO
+
+# When train model with multi machines, use "--config_file accelerate.yaml" instead of "--mixed_precision='bf16'".
+accelerate launch --mixed_precision="bf16" scripts/train.py \
+ --pretrained_model_name_or_path=$MODEL_NAME \
+ --train_data_dir=$DATASET_NAME \
+ --train_data_meta=$DATASET_META_NAME \
+ --image_sample_size=1280 \
+ --video_sample_size=256 \
+ --token_sample_size=512 \
+ --video_sample_stride=3 \
+ --video_sample_n_frames=49 \
+ --train_batch_size=4 \
+ --video_repeat=1 \
+ --gradient_accumulation_steps=1 \
+ --dataloader_num_workers=8 \
+ --num_train_epochs=100 \
+ --checkpointing_steps=50 \
+ --learning_rate=2e-05 \
+ --lr_scheduler="constant_with_warmup" \
+ --lr_warmup_steps=100 \
+ --seed=42 \
+ --output_dir="output_dir" \
+ --enable_xformers_memory_efficient_attention \
+ --gradient_checkpointing \
+ --mixed_precision="bf16" \
+ --adam_weight_decay=3e-2 \
+ --adam_epsilon=1e-10 \
+ --vae_mini_batch=1 \
+ --max_grad_norm=0.05 \
+ --random_hw_adapt \
+ --training_with_video_token_length \
+ --random_frame_crop \
+ --enable_bucket \
+ --use_came \
+ --use_ema \
+ --train_mode="inpaint" \
+ --resume_from_checkpoint="latest" \
+ --trainable_modules "."
+```
+
+CogVideoX-Arbitrary with deepspeed:
+```sh
+export MODEL_NAME="models/Diffusion_Transformer/CogVideoX-Fun-2b-InP"
+export DATASET_NAME="datasets/internal_datasets/"
+export DATASET_META_NAME="datasets/internal_datasets/metadata.json"
+export NCCL_IB_DISABLE=1
+export NCCL_P2P_DISABLE=1
+NCCL_DEBUG=INFO
+
+accelerate launch --use_deepspeed --deepspeed_config_file config/zero_stage2_config.json --deepspeed_multinode_launcher standard scripts/train.py \
+ --pretrained_model_name_or_path=$MODEL_NAME \
+ --train_data_dir=$DATASET_NAME \
+ --train_data_meta=$DATASET_META_NAME \
+ --image_sample_size=1280 \
+ --video_sample_size=256 \
+ --token_sample_size=512 \
+ --video_sample_stride=3 \
+ --video_sample_n_frames=49 \
+ --train_batch_size=4 \
+ --video_repeat=1 \
+ --gradient_accumulation_steps=1 \
+ --dataloader_num_workers=8 \
+ --num_train_epochs=100 \
+ --checkpointing_steps=50 \
+ --learning_rate=2e-05 \
+ --lr_scheduler="constant_with_warmup" \
+ --lr_warmup_steps=100 \
+ --seed=42 \
+ --output_dir="output_dir" \
+ --enable_xformers_memory_efficient_attention \
+ --gradient_checkpointing \
+ --mixed_precision="bf16" \
+ --adam_weight_decay=3e-2 \
+ --adam_epsilon=1e-10 \
+ --vae_mini_batch=1 \
+ --max_grad_norm=0.05 \
+ --random_hw_adapt \
+ --training_with_video_token_length \
+ --random_frame_crop \
+ --enable_bucket \
+ --use_came \
+ --use_deepspeed \
+ --use_ema \
+ --train_mode="inpaint" \
+ --resume_from_checkpoint="latest" \
+ --trainable_modules "."
+```
\ No newline at end of file
diff --git a/scripts/README_TRAIN_LORA.md b/scripts/README_TRAIN_LORA.md
new file mode 100644
index 0000000..67ee444
--- /dev/null
+++ b/scripts/README_TRAIN_LORA.md
@@ -0,0 +1,88 @@
+## Lora Training Code
+
+We can choose whether to use deep speed in CogVideoX-Arbitrary, which can save a lot of video memory.
+
+CogVideoX-Arbitrary without deepspeed:
+
+```sh
+export MODEL_NAME="models/Diffusion_Transformer/CogVideoX-Fun-2b-InP"
+export DATASET_NAME="datasets/internal_datasets/"
+export DATASET_META_NAME="datasets/internal_datasets/metadata.json"
+export NCCL_IB_DISABLE=1
+export NCCL_P2P_DISABLE=1
+NCCL_DEBUG=INFO
+
+# When train model with multi machines, use "--config_file accelerate.yaml" instead of "--mixed_precision='bf16'".
+accelerate launch --mixed_precision="bf16" scripts/train_lora.py \
+ --pretrained_model_name_or_path=$MODEL_NAME \
+ --train_data_dir=$DATASET_NAME \
+ --train_data_meta=$DATASET_META_NAME \
+ --image_sample_size=1280 \
+ --video_sample_size=256 \
+ --token_sample_size=512 \
+ --video_sample_stride=3 \
+ --video_sample_n_frames=49 \
+ --train_batch_size=1 \
+ --video_repeat=1 \
+ --gradient_accumulation_steps=1 \
+ --dataloader_num_workers=8 \
+ --num_train_epochs=100 \
+ --checkpointing_steps=50 \
+ --learning_rate=1e-04 \
+ --seed=42 \
+ --output_dir="output_dir" \
+ --gradient_checkpointing \
+ --mixed_precision="bf16" \
+ --adam_weight_decay=3e-2 \
+ --adam_epsilon=1e-10 \
+ --vae_mini_batch=1 \
+ --max_grad_norm=0.05 \
+ --random_hw_adapt \
+ --training_with_video_token_length \
+ --random_frame_crop \
+ --enable_bucket \
+ --low_vram \
+ --train_mode="inpaint"
+```
+
+```sh
+export MODEL_NAME="models/Diffusion_Transformer/CogVideoX-Fun-2b-InP"
+export DATASET_NAME="datasets/internal_datasets/"
+export DATASET_META_NAME="datasets/internal_datasets/metadata.json"
+export NCCL_IB_DISABLE=1
+export NCCL_P2P_DISABLE=1
+NCCL_DEBUG=INFO
+
+# When train model with multi machines, use "--config_file accelerate.yaml" instead of "--mixed_precision='bf16'".
+accelerate launch --use_deepspeed --deepspeed_config_file config/zero_stage2_config.json --deepspeed_multinode_launcher standard scripts/train_lora.py \
+ --pretrained_model_name_or_path=$MODEL_NAME \
+ --train_data_dir=$DATASET_NAME \
+ --train_data_meta=$DATASET_META_NAME \
+ --image_sample_size=1280 \
+ --video_sample_size=256 \
+ --token_sample_size=512 \
+ --video_sample_stride=3 \
+ --video_sample_n_frames=49 \
+ --train_batch_size=1 \
+ --video_repeat=1 \
+ --gradient_accumulation_steps=1 \
+ --dataloader_num_workers=8 \
+ --num_train_epochs=100 \
+ --checkpointing_steps=50 \
+ --learning_rate=1e-04 \
+ --seed=42 \
+ --output_dir="output_dir" \
+ --gradient_checkpointing \
+ --mixed_precision="bf16" \
+ --adam_weight_decay=3e-2 \
+ --adam_epsilon=1e-10 \
+ --vae_mini_batch=1 \
+ --max_grad_norm=0.05 \
+ --random_hw_adapt \
+ --training_with_video_token_length \
+ --random_frame_crop \
+ --enable_bucket \
+ --use_deepspeed \
+ --low_vram \
+ --train_mode="inpaint"
+```
diff --git a/scripts/train.py b/scripts/train.py
new file mode 100644
index 0000000..06e5acb
--- /dev/null
+++ b/scripts/train.py
@@ -0,0 +1,1704 @@
+"""Modified from https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image.py
+"""
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+
+import argparse
+import gc
+import logging
+import math
+import os
+import shutil
+import pickle
+import sys
+
+import accelerate
+import diffusers
+import numpy as np
+import torch
+import torch.nn.functional as F
+import torch.utils.checkpoint
+import transformers
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from accelerate.state import AcceleratorState
+from accelerate.utils import ProjectConfiguration, set_seed
+from diffusers import AutoencoderKL, DDPMScheduler, AutoencoderKLCogVideoX
+from diffusers.optimization import get_scheduler
+from diffusers.training_utils import EMAModel
+from diffusers.models.embeddings import get_3d_rotary_pos_embed
+from diffusers.utils import check_min_version, deprecate, is_wandb_available
+from diffusers.utils.import_utils import is_xformers_available
+from diffusers.utils.torch_utils import is_compiled_module
+from einops import rearrange
+from huggingface_hub import create_repo, upload_folder
+from omegaconf import OmegaConf
+from packaging import version
+from PIL import Image
+from torch.utils.data import RandomSampler
+from torch.utils.tensorboard import SummaryWriter
+from torchvision import transforms
+from tqdm.auto import tqdm
+from transformers import (BertModel, BertTokenizer, CLIPImageProcessor,
+ CLIPVisionModelWithProjection, MT5Tokenizer,
+ T5EncoderModel, T5Tokenizer)
+from transformers.utils import ContextManagers
+
+import datasets
+
+current_file_path = os.path.abspath(__file__)
+project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path))]
+for project_root in project_roots:
+ sys.path.insert(0, project_root) if project_root not in sys.path else None
+
+from cogvideox.data.bucket_sampler import (ASPECT_RATIO_512,
+ ASPECT_RATIO_RANDOM_CROP_512,
+ ASPECT_RATIO_RANDOM_CROP_PROB,
+ AspectRatioBatchImageVideoSampler,
+ RandomSampler, get_closest_ratio)
+from cogvideox.data.dataset_image_video import (ImageVideoDataset,
+ ImageVideoSampler,
+ get_random_mask)
+from cogvideox.models.transformer3d import CogVideoXTransformer3DModel
+from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_FUN_Pipeline
+from cogvideox.pipeline.pipeline_cogvideox_inpaint import CogVideoX_FUN_Pipeline_Inpaint
+from cogvideox.utils.utils import get_image_to_video_latent, save_videos_grid
+
+if is_wandb_available():
+ import wandb
+
+
+def get_random_downsample_ratio(sample_size, image_ratio=[],
+ all_choices=False, rng=None):
+ def _create_special_list(length):
+ if length == 1:
+ return [1.0]
+ if length >= 2:
+ first_element = 0.75
+ remaining_sum = 1.0 - first_element
+ other_elements_value = remaining_sum / (length - 1)
+ special_list = [first_element] + [other_elements_value] * (length - 1)
+ return special_list
+
+ if sample_size >= 1536:
+ number_list = [1, 1.25, 1.5, 2, 2.5, 3] + image_ratio
+ elif sample_size >= 1024:
+ number_list = [1, 1.25, 1.5, 2] + image_ratio
+ elif sample_size >= 768:
+ number_list = [1, 1.25, 1.5] + image_ratio
+ elif sample_size >= 512:
+ number_list = [1] + image_ratio
+ else:
+ number_list = [1]
+
+ if all_choices:
+ return number_list
+
+ number_list_prob = np.array(_create_special_list(len(number_list)))
+ if rng is None:
+ return np.random.choice(number_list, p = number_list_prob)
+ else:
+ return rng.choice(number_list, p = number_list_prob)
+
+def resize_mask(mask, latent, process_first_frame_only=True):
+ latent_size = latent.size()
+ batch_size, channels, num_frames, height, width = mask.shape
+
+ if process_first_frame_only:
+ target_size = list(latent_size[2:])
+ target_size[0] = 1
+ first_frame_resized = F.interpolate(
+ mask[:, :, 0:1, :, :],
+ size=target_size,
+ mode='trilinear',
+ align_corners=False
+ )
+
+ target_size = list(latent_size[2:])
+ target_size[0] = target_size[0] - 1
+ if target_size[0] != 0:
+ remaining_frames_resized = F.interpolate(
+ mask[:, :, 1:, :, :],
+ size=target_size,
+ mode='trilinear',
+ align_corners=False
+ )
+ resized_mask = torch.cat([first_frame_resized, remaining_frames_resized], dim=2)
+ else:
+ resized_mask = first_frame_resized
+ else:
+ target_size = list(latent_size[2:])
+ resized_mask = F.interpolate(
+ mask,
+ size=target_size,
+ mode='trilinear',
+ align_corners=False
+ )
+ return resized_mask
+
+# Will error if the minimal version of diffusers is not installed. Remove at your own risks.
+check_min_version("0.18.0.dev0")
+
+logger = get_logger(__name__, log_level="INFO")
+
+def log_validation(vae, text_encoder, tokenizer, transformer3d, args, accelerator, weight_dtype, global_step):
+ try:
+ logger.info("Running validation... ")
+
+ transformer3d_val = CogVideoXTransformer3DModel.from_pretrained_2d(
+ args.pretrained_model_name_or_path, subfolder="transformer"
+ ).to(weight_dtype)
+ transformer3d_val.load_state_dict(accelerator.unwrap_model(transformer3d).state_dict())
+
+ if args.train_mode != "normal":
+ pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
+ args.pretrained_model_name_or_path,
+ vae=accelerator.unwrap_model(vae).to(weight_dtype),
+ text_encoder=accelerator.unwrap_model(text_encoder),
+ tokenizer=tokenizer,
+ transformer=transformer3d_val,
+ torch_dtype=weight_dtype
+ )
+ else:
+ pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
+ args.pretrained_model_name_or_path,
+ vae=accelerator.unwrap_model(vae).to(weight_dtype),
+ text_encoder=accelerator.unwrap_model(text_encoder),
+ tokenizer=tokenizer,
+ transformer=transformer3d_val,
+ torch_dtype=weight_dtype
+ )
+ pipeline = pipeline.to(accelerator.device)
+
+ if args.seed is None:
+ generator = None
+ else:
+ generator = torch.Generator(device=accelerator.device).manual_seed(args.seed)
+
+ images = []
+ for i in range(len(args.validation_prompts)):
+ with torch.no_grad():
+ if args.train_mode != "normal":
+ with torch.autocast("cuda", dtype=weight_dtype):
+ video_length = int(args.video_sample_n_frames // vae.mini_batch_encoder * vae.mini_batch_encoder) if args.video_sample_n_frames != 1 else 1
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(None, None, video_length=video_length, sample_size=[args.video_sample_size, args.video_sample_size])
+ sample = pipeline(
+ args.validation_prompts[i],
+ video_length = args.video_sample_n_frames,
+ negative_prompt = "bad detailed",
+ height = args.video_sample_size,
+ width = args.video_sample_size,
+ guidance_scale = 6.0,
+ generator = generator,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ ).videos
+ os.makedirs(os.path.join(args.output_dir, "sample"), exist_ok=True)
+ save_videos_grid(sample, os.path.join(args.output_dir, f"sample/sample-{global_step}-{i}.gif"))
+
+ video_length = 1
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(None, None, video_length=video_length, sample_size=[args.video_sample_size, args.video_sample_size])
+ sample = pipeline(
+ args.validation_prompts[i],
+ video_length = 1,
+ negative_prompt = "bad detailed",
+ height = args.video_sample_size,
+ width = args.video_sample_size,
+ guidance_scale = 6.0,
+ generator = generator,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ ).videos
+ os.makedirs(os.path.join(args.output_dir, "sample"), exist_ok=True)
+ save_videos_grid(sample, os.path.join(args.output_dir, f"sample/sample-{global_step}-image-{i}.gif"))
+ else:
+ with torch.autocast("cuda", dtype=weight_dtype):
+ sample = pipeline(
+ args.validation_prompts[i],
+ video_length = args.video_sample_n_frames,
+ negative_prompt = "bad detailed",
+ height = args.video_sample_size,
+ width = args.video_sample_size,
+ generator = generator
+ ).videos
+ os.makedirs(os.path.join(args.output_dir, "sample"), exist_ok=True)
+ save_videos_grid(sample, os.path.join(args.output_dir, f"sample/sample-{global_step}-{i}.gif"))
+
+ sample = pipeline(
+ args.validation_prompts[i],
+ video_length = 1,
+ negative_prompt = "bad detailed",
+ height = args.video_sample_size,
+ width = args.video_sample_size,
+ generator = generator
+ ).videos
+ os.makedirs(os.path.join(args.output_dir, "sample"), exist_ok=True)
+ save_videos_grid(sample, os.path.join(args.output_dir, f"sample/sample-{global_step}-image-{i}.gif"))
+
+ del pipeline
+ del transformer3d_val
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.ipc_collect()
+
+ return images
+ except Exception as e:
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.ipc_collect()
+ print(f"Eval error with info {e}")
+ return None
+
+def linear_decay(initial_value, final_value, total_steps, current_step):
+ if current_step >= total_steps:
+ return final_value
+ current_step = max(0, current_step)
+ step_size = (final_value - initial_value) / total_steps
+ current_value = initial_value + step_size * current_step
+ return current_value
+
+def generate_timestep_with_lognorm(low, high, shape, device="cpu", generator=None):
+ u = torch.normal(mean=0.0, std=1.0, size=shape, device=device, generator=generator)
+ t = 1 / (1 + torch.exp(-u)) * (high - low) + low
+ return torch.clip(t.to(torch.int32), low, high - 1)
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Simple example of a training script.")
+ parser.add_argument(
+ "--input_perturbation", type=float, default=0, help="The scale of input perturbation. Recommended 0.1."
+ )
+ parser.add_argument(
+ "--pretrained_model_name_or_path",
+ type=str,
+ default=None,
+ required=True,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ )
+ parser.add_argument(
+ "--revision",
+ type=str,
+ default=None,
+ required=False,
+ help="Revision of pretrained model identifier from huggingface.co/models.",
+ )
+ parser.add_argument(
+ "--variant",
+ type=str,
+ default=None,
+ help="Variant of the model files of the pretrained model identifier from huggingface.co/models, 'e.g.' fp16",
+ )
+ parser.add_argument(
+ "--train_data_dir",
+ type=str,
+ default=None,
+ help=(
+ "A folder containing the training data. "
+ ),
+ )
+ parser.add_argument(
+ "--train_data_meta",
+ type=str,
+ default=None,
+ help=(
+ "A csv containing the training data. "
+ ),
+ )
+ parser.add_argument(
+ "--max_train_samples",
+ type=int,
+ default=None,
+ help=(
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ ),
+ )
+ parser.add_argument(
+ "--validation_prompts",
+ type=str,
+ default=None,
+ nargs="+",
+ help=("A set of prompts evaluated every `--validation_epochs` and logged to `--report_to`."),
+ )
+ parser.add_argument(
+ "--output_dir",
+ type=str,
+ default="sd-model-finetuned",
+ help="The output directory where the model predictions and checkpoints will be written.",
+ )
+ parser.add_argument(
+ "--cache_dir",
+ type=str,
+ default=None,
+ help="The directory where the downloaded models and datasets will be stored.",
+ )
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument(
+ "--random_flip",
+ action="store_true",
+ help="whether to randomly flip images horizontally",
+ )
+ parser.add_argument(
+ "--use_came",
+ action="store_true",
+ help="whether to use came",
+ )
+ parser.add_argument(
+ "--multi_stream",
+ action="store_true",
+ help="whether to use cuda multi-stream",
+ )
+ parser.add_argument(
+ "--train_batch_size", type=int, default=16, help="Batch size (per device) for the training dataloader."
+ )
+ parser.add_argument(
+ "--vae_mini_batch", type=int, default=32, help="mini batch size for vae."
+ )
+ parser.add_argument("--num_train_epochs", type=int, default=100)
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--gradient_checkpointing",
+ action="store_true",
+ help="Whether or not to use gradient checkpointing to save memory at the expense of slower backward pass.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=1e-4,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument(
+ "--scale_lr",
+ action="store_true",
+ default=False,
+ help="Scale the learning rate by the number of GPUs, gradient accumulation steps, and batch size.",
+ )
+ parser.add_argument(
+ "--lr_scheduler",
+ type=str,
+ default="constant",
+ help=(
+ 'The scheduler type to use. Choose between ["linear", "cosine", "cosine_with_restarts", "polynomial",'
+ ' "constant", "constant_with_warmup"]'
+ ),
+ )
+ parser.add_argument(
+ "--lr_warmup_steps", type=int, default=500, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument(
+ "--use_8bit_adam", action="store_true", help="Whether or not to use 8-bit Adam from bitsandbytes."
+ )
+ parser.add_argument(
+ "--allow_tf32",
+ action="store_true",
+ help=(
+ "Whether or not to allow TF32 on Ampere GPUs. Can be used to speed up training. For more information, see"
+ " https://pytorch.org/docs/stable/notes/cuda.html#tensorfloat-32-tf32-on-ampere-devices"
+ ),
+ )
+ parser.add_argument("--use_ema", action="store_true", help="Whether to use EMA model.")
+ parser.add_argument(
+ "--non_ema_revision",
+ type=str,
+ default=None,
+ required=False,
+ help=(
+ "Revision of pretrained non-ema model identifier. Must be a branch, tag or git identifier of the local or"
+ " remote repository specified with --pretrained_model_name_or_path."
+ ),
+ )
+ parser.add_argument(
+ "--dataloader_num_workers",
+ type=int,
+ default=0,
+ help=(
+ "Number of subprocesses to use for data loading. 0 means that the data will be loaded in the main process."
+ ),
+ )
+ parser.add_argument("--adam_beta1", type=float, default=0.9, help="The beta1 parameter for the Adam optimizer.")
+ parser.add_argument("--adam_beta2", type=float, default=0.999, help="The beta2 parameter for the Adam optimizer.")
+ parser.add_argument("--adam_weight_decay", type=float, default=1e-2, help="Weight decay to use.")
+ parser.add_argument("--adam_epsilon", type=float, default=1e-08, help="Epsilon value for the Adam optimizer")
+ parser.add_argument("--max_grad_norm", default=1.0, type=float, help="Max gradient norm.")
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument("--hub_token", type=str, default=None, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--prediction_type",
+ type=str,
+ default=None,
+ help="The prediction_type that shall be used for training. Choose between 'epsilon' or 'v_prediction' or leave `None`. If left to `None` the default prediction type of the scheduler: `noise_scheduler.config.prediciton_type` is chosen.",
+ )
+ parser.add_argument(
+ "--hub_model_id",
+ type=str,
+ default=None,
+ help="The name of the repository to keep in sync with the local `output_dir`.",
+ )
+ parser.add_argument(
+ "--logging_dir",
+ type=str,
+ default="logs",
+ help=(
+ "[TensorBoard](https://www.tensorflow.org/tensorboard) log directory. Will default to"
+ " *output_dir/runs/**CURRENT_DATETIME_HOSTNAME***."
+ ),
+ )
+ parser.add_argument(
+ "--report_model_info", action="store_true", help="Whether or not to report more info about model (such as norm, grad)."
+ )
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16"],
+ help=(
+ "Whether to use mixed precision. Choose between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >="
+ " 1.10.and an Nvidia Ampere GPU. Default to the value of accelerate config of the current system or the"
+ " flag passed with the `accelerate.launch` command. Use this argument to override the accelerate config."
+ ),
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="tensorboard",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`'
+ ' (default), `"wandb"` and `"comet_ml"`. Use `"all"` to report to all integrations.'
+ ),
+ )
+ parser.add_argument("--local_rank", type=int, default=-1, help="For distributed training: local_rank")
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=int,
+ default=500,
+ help=(
+ "Save a checkpoint of the training state every X updates. These checkpoints are only suitable for resuming"
+ " training using `--resume_from_checkpoint`."
+ ),
+ )
+ parser.add_argument(
+ "--checkpoints_total_limit",
+ type=int,
+ default=None,
+ help=("Max number of checkpoints to store."),
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help=(
+ "Whether training should be resumed from a previous checkpoint. Use a path saved by"
+ ' `--checkpointing_steps`, or `"latest"` to automatically select the last available checkpoint.'
+ ),
+ )
+ parser.add_argument("--noise_offset", type=float, default=0, help="The scale of noise offset.")
+ parser.add_argument(
+ "--validation_epochs",
+ type=int,
+ default=5,
+ help="Run validation every X epochs.",
+ )
+ parser.add_argument(
+ "--validation_steps",
+ type=int,
+ default=2000,
+ help="Run validation every X steps.",
+ )
+ parser.add_argument(
+ "--tracker_project_name",
+ type=str,
+ default="text2image-fine-tune",
+ help=(
+ "The `project_name` argument passed to Accelerator.init_trackers for"
+ " more information see https://huggingface.co/docs/accelerate/v0.17.0/en/package_reference/accelerator#accelerate.Accelerator"
+ ),
+ )
+
+ parser.add_argument(
+ "--snr_loss", action="store_true", help="Whether or not to use snr_loss."
+ )
+ parser.add_argument(
+ "--enable_text_encoder_in_dataloader", action="store_true", help="Whether or not to use text encoder in dataloader."
+ )
+ parser.add_argument(
+ "--enable_bucket", action="store_true", help="Whether enable bucket sample in datasets."
+ )
+ parser.add_argument(
+ "--random_ratio_crop", action="store_true", help="Whether enable random ratio crop sample in datasets."
+ )
+ parser.add_argument(
+ "--random_frame_crop", action="store_true", help="Whether enable random frame crop sample in datasets."
+ )
+ parser.add_argument(
+ "--random_hw_adapt", action="store_true", help="Whether enable random adapt height and width in datasets."
+ )
+ parser.add_argument(
+ "--training_with_video_token_length", action="store_true", help="The training stage of the model in training.",
+ )
+ parser.add_argument(
+ "--motion_sub_loss", action="store_true", help="Whether enable motion sub loss."
+ )
+ parser.add_argument(
+ "--motion_sub_loss_ratio", type=float, default=0.25, help="The ratio of motion sub loss."
+ )
+ parser.add_argument(
+ "--train_sampling_steps",
+ type=int,
+ default=1000,
+ help="Run train_sampling_steps.",
+ )
+ parser.add_argument(
+ "--keep_all_node_same_token_length",
+ action="store_true",
+ help="Reference of the length token.",
+ )
+ parser.add_argument(
+ "--token_sample_size",
+ type=int,
+ default=512,
+ help="Sample size of the token.",
+ )
+ parser.add_argument(
+ "--video_sample_size",
+ type=int,
+ default=512,
+ help="Sample size of the video.",
+ )
+ parser.add_argument(
+ "--image_sample_size",
+ type=int,
+ default=512,
+ help="Sample size of the video.",
+ )
+ parser.add_argument(
+ "--video_sample_stride",
+ type=int,
+ default=4,
+ help="Sample stride of the video.",
+ )
+ parser.add_argument(
+ "--video_sample_n_frames",
+ type=int,
+ default=17,
+ help="Num frame of video.",
+ )
+ parser.add_argument(
+ "--video_repeat",
+ type=int,
+ default=0,
+ help="Num of repeat video.",
+ )
+ parser.add_argument(
+ "--transformer_path",
+ type=str,
+ default=None,
+ help=("If you want to load the weight from other transformers, input its path."),
+ )
+ parser.add_argument(
+ "--vae_path",
+ type=str,
+ default=None,
+ help=("If you want to load the weight from other vaes, input its path."),
+ )
+
+ parser.add_argument(
+ '--trainable_modules',
+ nargs='+',
+ help='Enter a list of trainable modules'
+ )
+ parser.add_argument(
+ '--trainable_modules_low_learning_rate',
+ nargs='+',
+ default=[],
+ help='Enter a list of trainable modules with lower learning rate'
+ )
+ parser.add_argument(
+ '--tokenizer_max_length',
+ type=int,
+ default=226,
+ help='Max length of tokenizer'
+ )
+ parser.add_argument(
+ "--use_deepspeed", action="store_true", help="Whether or not to use deepspeed."
+ )
+ parser.add_argument(
+ "--low_vram", action="store_true", help="Whether enable low_vram mode."
+ )
+ parser.add_argument(
+ "--train_mode",
+ type=str,
+ default="normal",
+ help=(
+ 'The format of training data. Support `"normal"`'
+ ' (default), `"inpaint"`.'
+ ),
+ )
+ parser.add_argument(
+ "--abnormal_norm_clip_start",
+ type=int,
+ default=1000,
+ help=(
+ 'When do we start doing additional processing on abnormal gradients. '
+ ),
+ )
+ parser.add_argument(
+ "--initial_grad_norm_ratio",
+ type=int,
+ default=5,
+ help=(
+ 'The initial gradient is relative to the multiple of the max_grad_norm. '
+ ),
+ )
+
+ args = parser.parse_args()
+ env_local_rank = int(os.environ.get("LOCAL_RANK", -1))
+ if env_local_rank != -1 and env_local_rank != args.local_rank:
+ args.local_rank = env_local_rank
+
+ # default to using the same revision for the non-ema model if not specified
+ if args.non_ema_revision is None:
+ args.non_ema_revision = args.revision
+
+ return args
+
+
+def main():
+ args = parse_args()
+
+ if args.report_to == "wandb" and args.hub_token is not None:
+ raise ValueError(
+ "You cannot use both --report_to=wandb and --hub_token due to a security risk of exposing your token."
+ " Please use `huggingface-cli login` to authenticate with the Hub."
+ )
+
+ if args.non_ema_revision is not None:
+ deprecate(
+ "non_ema_revision!=None",
+ "0.15.0",
+ message=(
+ "Downloading 'non_ema' weights from revision branches of the Hub is deprecated. Please make sure to"
+ " use `--variant=non_ema` instead."
+ ),
+ )
+ logging_dir = os.path.join(args.output_dir, args.logging_dir)
+
+ accelerator_project_config = ProjectConfiguration(project_dir=args.output_dir, logging_dir=logging_dir)
+
+ accelerator = Accelerator(
+ gradient_accumulation_steps=args.gradient_accumulation_steps,
+ mixed_precision=args.mixed_precision,
+ log_with=args.report_to,
+ project_config=accelerator_project_config,
+ )
+ if accelerator.is_main_process:
+ writer = SummaryWriter(log_dir=logging_dir)
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_warning()
+ diffusers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+ diffusers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+ rng = np.random.default_rng(np.random.PCG64(args.seed + accelerator.process_index))
+ torch_rng = torch.Generator(accelerator.device).manual_seed(args.seed + accelerator.process_index)
+ else:
+ rng = None
+ torch_rng = None
+ index_rng = np.random.default_rng(np.random.PCG64(43))
+ print(f"Init rng with seed {args.seed + accelerator.process_index}. Process_index is {accelerator.process_index}")
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+
+ # For mixed precision training we cast all non-trainable weigths (vae, non-lora text_encoder and non-lora transformer3d) to half-precision
+ # as these weights are only used for inference, keeping weights in full precision is not required.
+ weight_dtype = torch.float32
+ if accelerator.mixed_precision == "fp16":
+ weight_dtype = torch.float16
+ args.mixed_precision = accelerator.mixed_precision
+ elif accelerator.mixed_precision == "bf16":
+ weight_dtype = torch.bfloat16
+ args.mixed_precision = accelerator.mixed_precision
+
+ # Load scheduler, tokenizer and models.
+ noise_scheduler = DDPMScheduler.from_pretrained(args.pretrained_model_name_or_path, subfolder="scheduler")
+
+ tokenizer = T5Tokenizer.from_pretrained(
+ args.pretrained_model_name_or_path, subfolder="tokenizer", revision=args.revision
+ )
+
+ def deepspeed_zero_init_disabled_context_manager():
+ """
+ returns either a context list that includes one that will disable zero.Init or an empty context list
+ """
+ deepspeed_plugin = AcceleratorState().deepspeed_plugin if accelerate.state.is_initialized() else None
+ if deepspeed_plugin is None:
+ return []
+
+ return [deepspeed_plugin.zero3_init_context_manager(enable=False)]
+
+ # Currently Accelerate doesn't know how to handle multiple models under Deepspeed ZeRO stage 3.
+ # For this to work properly all models must be run through `accelerate.prepare`. But accelerate
+ # will try to assign the same optimizer with the same weights to all models during
+ # `deepspeed.initialize`, which of course doesn't work.
+ #
+ # For now the following workaround will partially support Deepspeed ZeRO-3, by excluding the 2
+ # frozen models from being partitioned during `zero.Init` which gets called during
+ # `from_pretrained` So CLIPTextModel and AutoencoderKL will not enjoy the parameter sharding
+ # across multiple gpus and only UNet2DConditionModel will get ZeRO sharded.
+ with ContextManagers(deepspeed_zero_init_disabled_context_manager()):
+ text_encoder = T5EncoderModel.from_pretrained(
+ args.pretrained_model_name_or_path, subfolder="text_encoder", revision=args.revision, variant=args.variant,
+ torch_dtype=weight_dtype
+ )
+
+ vae = AutoencoderKLCogVideoX.from_pretrained(
+ args.pretrained_model_name_or_path, subfolder="vae", revision=args.revision, variant=args.variant
+ )
+
+ transformer3d = CogVideoXTransformer3DModel.from_pretrained_2d(
+ args.pretrained_model_name_or_path, subfolder="transformer"
+ )
+
+ # Freeze vae and text_encoder and set transformer3d to trainable
+ vae.requires_grad_(False)
+ text_encoder.requires_grad_(False)
+ transformer3d.requires_grad_(False)
+
+ if args.transformer_path is not None:
+ print(f"From checkpoint: {args.transformer_path}")
+ if args.transformer_path.endswith("safetensors"):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(args.transformer_path)
+ else:
+ state_dict = torch.load(args.transformer_path, map_location="cpu")
+ state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
+
+ m, u = transformer3d.load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+ assert len(u) == 0
+
+ if args.vae_path is not None:
+ print(f"From checkpoint: {args.vae_path}")
+ if args.vae_path.endswith("safetensors"):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(args.vae_path)
+ else:
+ state_dict = torch.load(args.vae_path, map_location="cpu")
+ state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
+
+ m, u = vae.load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+ assert len(u) == 0
+
+ # A good trainable modules is showed below now.
+ # For 3D Patch: trainable_modules = ['ff.net', 'pos_embed', 'attn2', 'proj_out', 'timepositionalencoding', 'h_position', 'w_position']
+ # For 2D Patch: trainable_modules = ['ff.net', 'attn2', 'timepositionalencoding', 'h_position', 'w_position']
+ transformer3d.train()
+ if accelerator.is_main_process:
+ accelerator.print(
+ f"Trainable modules '{args.trainable_modules}'."
+ )
+ for name, param in transformer3d.named_parameters():
+ for trainable_module_name in args.trainable_modules + args.trainable_modules_low_learning_rate:
+ if trainable_module_name in name:
+ param.requires_grad = True
+ break
+
+ # Create EMA for the transformer3d.
+ if args.use_ema:
+ ema_transformer3d = CogVideoXTransformer3DModel.from_pretrained_2d(
+ args.pretrained_model_name_or_path, subfolder="transformer"
+ )
+ ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=CogVideoXTransformer3DModel, model_config=ema_transformer3d.config)
+
+ # `accelerate` 0.16.0 will have better support for customized saving
+ if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
+ # create custom saving & loading hooks so that `accelerator.save_state(...)` serializes in a nice format
+ def save_model_hook(models, weights, output_dir):
+ if accelerator.is_main_process:
+ if args.use_ema:
+ ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
+
+ models[0].save_pretrained(os.path.join(output_dir, "transformer"))
+ if not args.use_deepspeed:
+ weights.pop()
+
+ with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
+ pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
+
+ def load_model_hook(models, input_dir):
+ if args.use_ema:
+ ema_path = os.path.join(input_dir, "transformer_ema")
+ _, ema_kwargs = CogVideoXTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
+ load_model = CogVideoXTransformer3DModel.from_pretrained_2d(
+ input_dir, subfolder="transformer_ema"
+ )
+ load_model = EMAModel(load_model.parameters(), model_cls=CogVideoXTransformer3DModel, model_config=load_model.config)
+ load_model.load_state_dict(ema_kwargs)
+
+ ema_transformer3d.load_state_dict(load_model.state_dict())
+ ema_transformer3d.to(accelerator.device)
+ del load_model
+
+ for i in range(len(models)):
+ # pop models so that they are not loaded again
+ model = models.pop()
+
+ # load diffusers style into model
+ load_model = CogVideoXTransformer3DModel.from_pretrained_2d(
+ input_dir, subfolder="transformer"
+ )
+ model.register_to_config(**load_model.config)
+
+ model.load_state_dict(load_model.state_dict())
+ del load_model
+
+ pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
+ if os.path.exists(pkl_path):
+ with open(pkl_path, 'rb') as file:
+ loaded_number, _ = pickle.load(file)
+ batch_sampler.sampler._pos_start = max(loaded_number - args.dataloader_num_workers * accelerator.num_processes * 2, 0)
+ print(f"Load pkl from {pkl_path}. Get loaded_number = {loaded_number}.")
+
+ accelerator.register_save_state_pre_hook(save_model_hook)
+ accelerator.register_load_state_pre_hook(load_model_hook)
+
+ if args.gradient_checkpointing:
+ transformer3d.enable_gradient_checkpointing()
+
+ # Enable TF32 for faster training on Ampere GPUs,
+ # cf https://pytorch.org/docs/stable/notes/cuda.html#tensorfloat-32-tf32-on-ampere-devices
+ if args.allow_tf32:
+ torch.backends.cuda.matmul.allow_tf32 = True
+
+ if args.scale_lr:
+ args.learning_rate = (
+ args.learning_rate * args.gradient_accumulation_steps * args.train_batch_size * accelerator.num_processes
+ )
+
+ # Initialize the optimizer
+ if args.use_8bit_adam:
+ try:
+ import bitsandbytes as bnb
+ except ImportError:
+ raise ImportError(
+ "Please install bitsandbytes to use 8-bit Adam. You can do so by running `pip install bitsandbytes`"
+ )
+
+ optimizer_cls = bnb.optim.AdamW8bit
+ elif args.use_came:
+ try:
+ from came_pytorch import CAME
+ except:
+ raise ImportError(
+ "Please install came_pytorch to use CAME. You can do so by running `pip install came_pytorch`"
+ )
+
+ optimizer_cls = CAME
+ else:
+ optimizer_cls = torch.optim.AdamW
+
+ trainable_params = list(filter(lambda p: p.requires_grad, transformer3d.parameters()))
+ trainable_params_optim = [
+ {'params': [], 'lr': args.learning_rate},
+ {'params': [], 'lr': args.learning_rate / 2},
+ ]
+ in_already = []
+ for name, param in transformer3d.named_parameters():
+ high_lr_flag = False
+ if name in in_already:
+ continue
+ for trainable_module_name in args.trainable_modules:
+ if trainable_module_name in name:
+ in_already.append(name)
+ high_lr_flag = True
+ trainable_params_optim[0]['params'].append(param)
+ if accelerator.is_main_process:
+ print(f"Set {name} to lr : {args.learning_rate}")
+ break
+ if high_lr_flag:
+ continue
+ for trainable_module_name in args.trainable_modules_low_learning_rate:
+ if trainable_module_name in name:
+ in_already.append(name)
+ trainable_params_optim[1]['params'].append(param)
+ if accelerator.is_main_process:
+ print(f"Set {name} to lr : {args.learning_rate / 2}")
+ break
+
+ if args.use_came:
+ optimizer = optimizer_cls(
+ trainable_params_optim,
+ lr=args.learning_rate,
+ # weight_decay=args.adam_weight_decay,
+ betas=(0.9, 0.999, 0.9999),
+ eps=(1e-30, 1e-16)
+ )
+ else:
+ optimizer = optimizer_cls(
+ trainable_params_optim,
+ lr=args.learning_rate,
+ betas=(args.adam_beta1, args.adam_beta2),
+ weight_decay=args.adam_weight_decay,
+ eps=args.adam_epsilon,
+ )
+
+ # Get the training dataset
+ sample_n_frames_bucket_interval = 4
+
+ train_dataset = ImageVideoDataset(
+ args.train_data_meta, args.train_data_dir,
+ video_sample_size=args.video_sample_size, video_sample_stride=args.video_sample_stride, video_sample_n_frames=args.video_sample_n_frames,
+ video_repeat=args.video_repeat,
+ image_sample_size=args.image_sample_size,
+ enable_bucket=args.enable_bucket, enable_inpaint=True if args.train_mode != "normal" else False,
+ )
+
+ if args.enable_bucket:
+ aspect_ratio_sample_size = {key : [x / 512 * args.video_sample_size for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ aspect_ratio_random_crop_sample_size = {key : [x / 512 * args.video_sample_size for x in ASPECT_RATIO_RANDOM_CROP_512[key]] for key in ASPECT_RATIO_RANDOM_CROP_512.keys()}
+
+ batch_sampler_generator = torch.Generator().manual_seed(args.seed)
+ batch_sampler = AspectRatioBatchImageVideoSampler(
+ sampler=RandomSampler(train_dataset, generator=batch_sampler_generator), dataset=train_dataset.dataset,
+ batch_size=args.train_batch_size, train_folder = args.train_data_dir, drop_last=True,
+ aspect_ratios=aspect_ratio_sample_size,
+ )
+ if args.keep_all_node_same_token_length:
+ if args.token_sample_size > 256:
+ numbers_list = list(range(256, args.token_sample_size + 1, 128))
+
+ if numbers_list[-1] != args.token_sample_size:
+ numbers_list.append(args.token_sample_size)
+ else:
+ numbers_list = [256]
+ numbers_list = [_number * _number * args.video_sample_n_frames for _number in numbers_list]
+ else:
+ numbers_list = None
+
+ def get_length_to_frame_num(token_length):
+ if args.image_sample_size > args.video_sample_size:
+ sample_sizes = list(range(256, args.image_sample_size + 1, 128))
+
+ if sample_sizes[-1] != args.image_sample_size:
+ sample_sizes.append(args.image_sample_size)
+ else:
+ sample_sizes = [256]
+
+ length_to_frame_num = {
+ sample_size: min(token_length / sample_size / sample_size, args.video_sample_n_frames) // sample_n_frames_bucket_interval * sample_n_frames_bucket_interval + 1 for sample_size in sample_sizes
+ }
+
+ return length_to_frame_num
+
+ def collate_fn(examples):
+ target_token_length = args.video_sample_n_frames * args.token_sample_size * args.token_sample_size
+ length_to_frame_num = get_length_to_frame_num(
+ target_token_length,
+ )
+
+ # Create new output
+ new_examples = {}
+ new_examples["target_token_length"] = target_token_length
+ new_examples["pixel_values"] = []
+ new_examples["text"] = []
+ if args.train_mode != "normal":
+ new_examples["mask_pixel_values"] = []
+ new_examples["mask"] = []
+
+ # Get ratio
+ pixel_value = examples[0]["pixel_values"]
+ data_type = examples[0]["data_type"]
+ f, h, w, c = np.shape(pixel_value)
+ if data_type == 'image':
+ random_downsample_ratio = 1 if not args.random_hw_adapt else get_random_downsample_ratio(args.image_sample_size, image_ratio=[args.image_sample_size / args.video_sample_size], rng=rng)
+
+ aspect_ratio_sample_size = {key : [x / 512 * args.image_sample_size / random_downsample_ratio for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ aspect_ratio_random_crop_sample_size = {key : [x / 512 * args.image_sample_size / random_downsample_ratio for x in ASPECT_RATIO_RANDOM_CROP_512[key]] for key in ASPECT_RATIO_RANDOM_CROP_512.keys()}
+
+ batch_video_length = args.video_sample_n_frames + sample_n_frames_bucket_interval
+ else:
+ if args.random_hw_adapt:
+ if args.training_with_video_token_length:
+ local_min_size = np.min(np.array([np.mean(np.array([np.shape(example["pixel_values"])[1], np.shape(example["pixel_values"])[2]])) for example in examples]))
+ choice_list = [length for length in list(length_to_frame_num.keys()) if length < local_min_size * 1.25]
+ if len(choice_list) == 0:
+ choice_list = list(length_to_frame_num.keys())
+ if rng is None:
+ local_video_sample_size = np.random.choice(choice_list)
+ else:
+ local_video_sample_size = rng.choice(choice_list)
+ batch_video_length = length_to_frame_num[local_video_sample_size]
+ random_downsample_ratio = args.video_sample_size / local_video_sample_size
+ else:
+ random_downsample_ratio = get_random_downsample_ratio(
+ args.video_sample_size, rng=rng)
+ batch_video_length = args.video_sample_n_frames + sample_n_frames_bucket_interval
+ else:
+ random_downsample_ratio = 1
+ batch_video_length = args.video_sample_n_frames + sample_n_frames_bucket_interval
+
+ aspect_ratio_sample_size = {key : [x / 512 * args.video_sample_size / random_downsample_ratio for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ aspect_ratio_random_crop_sample_size = {key : [x / 512 * args.video_sample_size / random_downsample_ratio for x in ASPECT_RATIO_RANDOM_CROP_512[key]] for key in ASPECT_RATIO_RANDOM_CROP_512.keys()}
+
+ closest_size, closest_ratio = get_closest_ratio(h, w, ratios=aspect_ratio_sample_size)
+ closest_size = [int(x / 16) * 16 for x in closest_size]
+ if args.random_ratio_crop:
+ if rng is None:
+ random_sample_size = aspect_ratio_random_crop_sample_size[
+ np.random.choice(list(aspect_ratio_random_crop_sample_size.keys()), p = ASPECT_RATIO_RANDOM_CROP_PROB)
+ ]
+ else:
+ random_sample_size = aspect_ratio_random_crop_sample_size[
+ rng.choice(list(aspect_ratio_random_crop_sample_size.keys()), p = ASPECT_RATIO_RANDOM_CROP_PROB)
+ ]
+ random_sample_size = [int(x / 16) * 16 for x in random_sample_size]
+
+ for example in examples:
+ if args.random_ratio_crop:
+ # To 0~1
+ pixel_values = torch.from_numpy(example["pixel_values"]).permute(0, 3, 1, 2).contiguous()
+ pixel_values = pixel_values / 255.
+
+ # Get adapt hw for resize
+ b, c, h, w = pixel_values.size()
+ th, tw = random_sample_size
+ if th / tw > h / w:
+ nh = int(th)
+ nw = int(w / h * nh)
+ else:
+ nw = int(tw)
+ nh = int(h / w * nw)
+
+ transform = transforms.Compose([
+ transforms.Resize([nh, nw]),
+ transforms.CenterCrop([int(x) for x in random_sample_size]),
+ transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
+ ])
+ else:
+ closest_size = list(map(lambda x: int(x), closest_size))
+ if closest_size[0] / h > closest_size[1] / w:
+ resize_size = closest_size[0], int(w * closest_size[0] / h)
+ else:
+ resize_size = int(h * closest_size[1] / w), closest_size[1]
+
+ pixel_values = torch.from_numpy(example["pixel_values"]).permute(0, 3, 1, 2).contiguous()
+ pixel_values = pixel_values / 255.
+ transform = transforms.Compose([
+ transforms.Resize(resize_size, interpolation=transforms.InterpolationMode.BILINEAR), # Image.BICUBIC
+ transforms.CenterCrop(closest_size),
+ transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
+ ])
+ new_examples["pixel_values"].append(transform(pixel_values))
+ new_examples["text"].append(example["text"])
+ batch_video_length = int(
+ min(
+ batch_video_length,
+ (len(pixel_values) - 1) // sample_n_frames_bucket_interval * sample_n_frames_bucket_interval + 1,
+ )
+ )
+
+ if batch_video_length == 0:
+ batch_video_length = 1
+
+ if args.train_mode != "normal":
+ mask = get_random_mask(new_examples["pixel_values"][-1].size())
+ mask_pixel_values = new_examples["pixel_values"][-1] * (1 - mask) + torch.ones_like(new_examples["pixel_values"][-1]) * -1 * mask
+ new_examples["mask_pixel_values"].append(mask_pixel_values)
+ new_examples["mask"].append(mask)
+
+ new_examples["pixel_values"] = torch.stack([example[:batch_video_length] for example in new_examples["pixel_values"]])
+ if args.train_mode != "normal":
+ new_examples["mask_pixel_values"] = torch.stack([example[:batch_video_length] for example in new_examples["mask_pixel_values"]])
+ new_examples["mask"] = torch.stack([example[:batch_video_length] for example in new_examples["mask"]])
+
+ if args.enable_text_encoder_in_dataloader:
+ prompt_ids = tokenizer(
+ new_examples['text'],
+ max_length=args.tokenizer_max_length,
+ padding="max_length",
+ add_special_tokens=True,
+ truncation=True,
+ return_tensors="pt"
+ )
+ encoder_hidden_states = text_encoder(
+ prompt_ids.input_ids,
+ return_dict=False
+ )[0]
+ new_examples['encoder_attention_mask'] = prompt_ids.attention_mask
+ new_examples['encoder_hidden_states'] = encoder_hidden_states
+
+ return new_examples
+
+ # DataLoaders creation:
+ train_dataloader = torch.utils.data.DataLoader(
+ train_dataset,
+ batch_sampler=batch_sampler,
+ collate_fn=collate_fn,
+ persistent_workers=True if args.dataloader_num_workers != 0 else False,
+ num_workers=args.dataloader_num_workers,
+ )
+ else:
+ # DataLoaders creation:
+ batch_sampler_generator = torch.Generator().manual_seed(args.seed)
+ batch_sampler = ImageVideoSampler(RandomSampler(train_dataset, generator=batch_sampler_generator), train_dataset, args.train_batch_size)
+ train_dataloader = torch.utils.data.DataLoader(
+ train_dataset,
+ batch_sampler=batch_sampler,
+ persistent_workers=True if args.dataloader_num_workers != 0 else False,
+ num_workers=args.dataloader_num_workers,
+ )
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ args.lr_scheduler,
+ optimizer=optimizer,
+ num_warmup_steps=args.lr_warmup_steps * accelerator.num_processes,
+ num_training_steps=args.max_train_steps * accelerator.num_processes,
+ )
+
+ # Prepare everything with our `accelerator`.
+ transformer3d, optimizer, train_dataloader, lr_scheduler = accelerator.prepare(
+ transformer3d, optimizer, train_dataloader, lr_scheduler
+ )
+
+ if args.use_ema:
+ ema_transformer3d.to(accelerator.device)
+
+ # Move text_encode and vae to gpu and cast to weight_dtype
+ vae.to(accelerator.device, dtype=weight_dtype)
+ if not args.enable_text_encoder_in_dataloader:
+ text_encoder.to(accelerator.device)
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if accelerator.is_main_process:
+ tracker_config = dict(vars(args))
+ tracker_config.pop("validation_prompts")
+ tracker_config.pop("trainable_modules")
+ tracker_config.pop("trainable_modules_low_learning_rate")
+ accelerator.init_trackers(args.tracker_project_name, tracker_config)
+
+ # Function for unwrapping if model was compiled with `torch.compile`.
+ def unwrap_model(model):
+ model = accelerator.unwrap_model(model)
+ model = model._orig_mod if is_compiled_module(model) else model
+ return model
+
+ # Train!
+ total_batch_size = args.train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ global_step = 0
+ first_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint != "latest":
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = os.listdir(args.output_dir)
+ dirs = [d for d in dirs if d.startswith("checkpoint")]
+ dirs = sorted(dirs, key=lambda x: int(x.split("-")[1]))
+ path = dirs[-1] if len(dirs) > 0 else None
+
+ if path is None:
+ accelerator.print(
+ f"Checkpoint '{args.resume_from_checkpoint}' does not exist. Starting a new training run."
+ )
+ args.resume_from_checkpoint = None
+ initial_global_step = 0
+ else:
+ global_step = int(path.split("-")[1])
+
+ initial_global_step = global_step
+
+ pkl_path = os.path.join(os.path.join(args.output_dir, path), "sampler_pos_start.pkl")
+ if os.path.exists(pkl_path):
+ with open(pkl_path, 'rb') as file:
+ _, first_epoch = pickle.load(file)
+ else:
+ first_epoch = global_step // num_update_steps_per_epoch
+ print(f"Load pkl from {pkl_path}. Get first_epoch = {first_epoch}.")
+
+ accelerator.print(f"Resuming from checkpoint {path}")
+ accelerator.load_state(os.path.join(args.output_dir, path))
+ else:
+ initial_global_step = 0
+
+ progress_bar = tqdm(
+ range(0, args.max_train_steps),
+ initial=initial_global_step,
+ desc="Steps",
+ # Only show the progress bar once on each machine.
+ disable=not accelerator.is_local_main_process,
+ )
+
+ if args.multi_stream and args.train_mode != "normal":
+ # create extra cuda streams to speedup inpaint vae computation
+ vae_stream_1 = torch.cuda.Stream()
+ vae_stream_2 = torch.cuda.Stream()
+ else:
+ vae_stream_1 = None
+ vae_stream_2 = None
+
+ for epoch in range(first_epoch, args.num_train_epochs):
+ train_loss = 0.0
+ batch_sampler.sampler.generator = torch.Generator().manual_seed(args.seed + epoch)
+ for step, batch in enumerate(train_dataloader):
+ # Data batch sanity check
+ if epoch == first_epoch and step == 0:
+ pixel_values, texts = batch['pixel_values'].cpu(), batch['text']
+ pixel_values = rearrange(pixel_values, "b f c h w -> b c f h w")
+ os.makedirs(os.path.join(args.output_dir, "sanity_check"), exist_ok=True)
+ for idx, (pixel_value, text) in enumerate(zip(pixel_values, texts)):
+ pixel_value = pixel_value[None, ...]
+ gif_name = '-'.join(text.replace('/', '').split()[:10]) if not text == '' else f'{global_step}-{idx}'
+ save_videos_grid(pixel_value, f"{args.output_dir}/sanity_check/{gif_name[:10]}.gif", rescale=True)
+ if args.train_mode != "normal":
+ mask_pixel_values, texts = batch['mask_pixel_values'].cpu(), batch['text']
+ mask_pixel_values = rearrange(mask_pixel_values, "b f c h w -> b c f h w")
+ for idx, (pixel_value, text) in enumerate(zip(mask_pixel_values, texts)):
+ pixel_value = pixel_value[None, ...]
+ save_videos_grid(pixel_value, f"{args.output_dir}/sanity_check/mask_{gif_name[:10] if not text == '' else f'{global_step}-{idx}'}.gif", rescale=True)
+
+ with accelerator.accumulate(transformer3d):
+ # Convert images to latent space
+ pixel_values = batch["pixel_values"].to(weight_dtype)
+ if args.training_with_video_token_length:
+ if args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 16 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
+ pixel_values = torch.tile(pixel_values, (4, 1, 1, 1, 1))
+ if args.enable_text_encoder_in_dataloader:
+ batch['encoder_hidden_states'] = torch.tile(batch['encoder_hidden_states'], (4, 1, 1))
+ batch['encoder_attention_mask'] = torch.tile(batch['encoder_attention_mask'], (4, 1))
+ else:
+ batch['text'] = batch['text'] * 4
+ elif args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 4 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
+ pixel_values = torch.tile(pixel_values, (2, 1, 1, 1, 1))
+ if args.enable_text_encoder_in_dataloader:
+ batch['encoder_hidden_states'] = torch.tile(batch['encoder_hidden_states'], (2, 1, 1))
+ batch['encoder_attention_mask'] = torch.tile(batch['encoder_attention_mask'], (2, 1))
+ else:
+ batch['text'] = batch['text'] * 2
+
+ if args.train_mode != "normal":
+ mask_pixel_values = batch["mask_pixel_values"].to(weight_dtype)
+ mask = batch["mask"].to(weight_dtype)
+ if args.training_with_video_token_length:
+ if args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 16 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
+ mask_pixel_values = torch.tile(mask_pixel_values, (4, 1, 1, 1, 1))
+ mask = torch.tile(mask, (4, 1, 1, 1, 1))
+ elif args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 4 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
+ mask_pixel_values = torch.tile(mask_pixel_values, (2, 1, 1, 1, 1))
+ mask = torch.tile(mask, (2, 1, 1, 1, 1))
+
+ def create_special_list(length):
+ if length == 1:
+ return [1.0]
+ if length >= 2:
+ last_element = 0.90
+ remaining_sum = 1.0 - last_element
+ other_elements_value = remaining_sum / (length - 1)
+ special_list = [other_elements_value] * (length - 1) + [last_element]
+ return special_list
+
+ if args.keep_all_node_same_token_length:
+ actual_token_length = index_rng.choice(numbers_list)
+
+ actual_video_length = (min(
+ actual_token_length / pixel_values.size()[-1] / pixel_values.size()[-2], args.video_sample_n_frames
+ ) - 1) // sample_n_frames_bucket_interval * sample_n_frames_bucket_interval + 1
+ actual_video_length = int(max(actual_video_length, 1))
+ else:
+ actual_video_length = None
+
+ if args.random_frame_crop:
+ select_frames = [_tmp for _tmp in list(range(sample_n_frames_bucket_interval + 1, args.video_sample_n_frames + sample_n_frames_bucket_interval, sample_n_frames_bucket_interval))]
+ select_frames_prob = np.array(create_special_list(len(select_frames)))
+
+ if rng is None:
+ temp_n_frames = np.random.choice(select_frames, p = select_frames_prob)
+ else:
+ temp_n_frames = rng.choice(select_frames, p = select_frames_prob)
+ if args.keep_all_node_same_token_length:
+ temp_n_frames = min(actual_video_length, temp_n_frames)
+
+ pixel_values = pixel_values[:, :temp_n_frames, :, :]
+
+ if args.train_mode != "normal":
+ mask_pixel_values = mask_pixel_values[:, :temp_n_frames, :, :]
+ mask = mask[:, :temp_n_frames, :, :]
+
+ if args.train_mode != "normal":
+ t2v_flag = [(_mask == 1).all() for _mask in mask]
+ new_t2v_flag = []
+ for _mask in t2v_flag:
+ if _mask and np.random.rand() < 0.90:
+ new_t2v_flag.append(0)
+ else:
+ new_t2v_flag.append(1)
+ t2v_flag = torch.from_numpy(np.array(new_t2v_flag)).to(accelerator.device, dtype=weight_dtype)
+
+ if args.low_vram:
+ torch.cuda.empty_cache()
+ vae.to(accelerator.device)
+ if not args.enable_text_encoder_in_dataloader:
+ text_encoder.to(accelerator.device)
+
+ with torch.no_grad():
+ # This way is quicker when batch grows up
+ def _slice_vae(pixel_values):
+ pixel_values = rearrange(pixel_values, "b f c h w -> b c f h w")
+ bs = args.vae_mini_batch
+ new_pixel_values = []
+ for i in range(0, pixel_values.shape[0], bs):
+ pixel_values_bs = pixel_values[i : i + bs]
+ pixel_values_bs = vae.encode(pixel_values_bs)[0]
+ pixel_values_bs = pixel_values_bs.sample()
+ new_pixel_values.append(pixel_values_bs)
+ vae._clear_fake_context_parallel_cache()
+ return torch.cat(new_pixel_values, dim = 0)
+ if vae_stream_1 is not None:
+ vae_stream_1.wait_stream(torch.cuda.current_stream())
+ with torch.cuda.stream(vae_stream_1):
+ latents = _slice_vae(pixel_values)
+ else:
+ latents = _slice_vae(pixel_values)
+ latents = latents * vae.config.scaling_factor
+
+ if args.train_mode != "normal":
+ mask = rearrange(mask, "b f c h w -> b c f h w")
+ mask = 1 - mask
+ mask = resize_mask(mask, latents)
+
+ mask_pixel_values = rearrange(mask_pixel_values, "b f c h w -> b c f h w")
+ bs = args.vae_mini_batch
+ new_mask_pixel_values = []
+ for i in range(0, mask_pixel_values.shape[0], bs):
+ mask_pixel_values_bs = mask_pixel_values[i : i + bs]
+ mask_pixel_values_bs = vae.encode(mask_pixel_values_bs)[0]
+ mask_pixel_values_bs = mask_pixel_values_bs.sample()
+ new_mask_pixel_values.append(mask_pixel_values_bs)
+ vae._clear_fake_context_parallel_cache()
+ mask_latents = torch.cat(new_mask_pixel_values, dim = 0)
+
+ if vae_stream_2 is not None:
+ torch.cuda.current_stream().wait_stream(vae_stream_2)
+
+ inpaint_latents = torch.concat([mask, mask_latents], dim=1)
+ inpaint_latents = t2v_flag[:, None, None, None, None] * inpaint_latents
+ inpaint_latents = inpaint_latents * vae.config.scaling_factor
+ inpaint_latents = rearrange(inpaint_latents, "b c f h w -> b f c h w")
+
+ latents = rearrange(latents, "b c f h w -> b f c h w")
+
+ # wait for latents = vae.encode(pixel_values) to complete
+ if vae_stream_1 is not None:
+ torch.cuda.current_stream().wait_stream(vae_stream_1)
+
+ if args.low_vram:
+ vae.to('cpu')
+ torch.cuda.empty_cache()
+ if not args.enable_text_encoder_in_dataloader:
+ text_encoder.to(accelerator.device)
+
+ if args.enable_text_encoder_in_dataloader:
+ prompt_embeds = batch['encoder_hidden_states'].to(device=latents.device)
+ else:
+ with torch.no_grad():
+ prompt_ids = tokenizer(
+ batch['text'],
+ max_length=args.tokenizer_max_length,
+ padding="max_length",
+ add_special_tokens=True,
+ truncation=True,
+ return_tensors="pt"
+ )
+ prompt_embeds = text_encoder(
+ prompt_ids.input_ids.to(latents.device),
+ return_dict=False
+ )[0]
+
+ if args.low_vram and not args.enable_text_encoder_in_dataloader:
+ text_encoder.to('cpu')
+ torch.cuda.empty_cache()
+
+ bsz = latents.shape[0]
+ noise = torch.randn(latents.size(), device=latents.device, generator=torch_rng, dtype=weight_dtype)
+ # Sample a random timestep for each image
+ # timesteps = generate_timestep_with_lognorm(0, args.train_sampling_steps, (bsz,), device=latents.device, generator=torch_rng)
+ timesteps = torch.randint(0, args.train_sampling_steps, (bsz,), device=latents.device, generator=torch_rng)
+ timesteps = timesteps.long()
+
+ # Similar to diffusers.pipelines.hunyuandit.pipeline_hunyuandit.get_resize_crop_region_for_grid
+ def get_resize_crop_region_for_grid(src, tgt_width, tgt_height):
+ tw = tgt_width
+ th = tgt_height
+ h, w = src
+ r = h / w
+ if r > (th / tw):
+ resize_height = th
+ resize_width = int(round(th / h * w))
+ else:
+ resize_width = tw
+ resize_height = int(round(tw / w * h))
+
+ crop_top = int(round((th - resize_height) / 2.0))
+ crop_left = int(round((tw - resize_width) / 2.0))
+
+ return (crop_top, crop_left), (crop_top + resize_height, crop_left + resize_width)
+
+ def _prepare_rotary_positional_embeddings(
+ height: int,
+ width: int,
+ num_frames: int,
+ device: torch.device
+ ):
+ vae_scale_factor_spatial = (
+ 2 ** (len(vae.config.block_out_channels) - 1) if vae is not None else 8
+ )
+ grid_height = height // (vae_scale_factor_spatial * unwrap_model(transformer3d).config.patch_size)
+ grid_width = width // (vae_scale_factor_spatial * unwrap_model(transformer3d).config.patch_size)
+ base_size_width = 720 // (vae_scale_factor_spatial * unwrap_model(transformer3d).config.patch_size)
+ base_size_height = 480 // (vae_scale_factor_spatial * unwrap_model(transformer3d).config.patch_size)
+
+ grid_crops_coords = get_resize_crop_region_for_grid(
+ (grid_height, grid_width), base_size_width, base_size_height
+ )
+ freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
+ embed_dim=transformer3d.config.attention_head_dim,
+ crops_coords=grid_crops_coords,
+ grid_size=(grid_height, grid_width),
+ temporal_size=num_frames,
+ use_real=True,
+ )
+ freqs_cos = freqs_cos.to(device=device)
+ freqs_sin = freqs_sin.to(device=device)
+ return freqs_cos, freqs_sin
+
+ height, width = batch["pixel_values"].size()[-2], batch["pixel_values"].size()[-1]
+ # 7. Create rotary embeds if required
+ image_rotary_emb = (
+ _prepare_rotary_positional_embeddings(height, width, latents.size(1), latents.device)
+ if unwrap_model(transformer3d).config.use_rotary_positional_embeddings
+ else None
+ )
+ prompt_embeds = prompt_embeds.to(device=latents.device)
+
+ noisy_latents = noise_scheduler.add_noise(latents, noise, timesteps)
+ if noise_scheduler.config.prediction_type == "epsilon":
+ target = noise
+ elif noise_scheduler.config.prediction_type == "v_prediction":
+ target = noise_scheduler.get_velocity(latents, noise, timesteps)
+ else:
+ raise ValueError(f"Unknown prediction type {noise_scheduler.config.prediction_type}")
+
+ # predict the noise residual
+ noise_pred = transformer3d(
+ hidden_states=noisy_latents,
+ encoder_hidden_states=prompt_embeds,
+ timestep=timesteps,
+ image_rotary_emb=image_rotary_emb,
+ return_dict=False,
+ inpaint_latents=inpaint_latents if args.train_mode != "normal" else None,
+ )[0]
+ print(noise_pred.size(), noisy_latents.size(), latents.size(), pixel_values.size())
+ loss = F.mse_loss(noise_pred.float(), target.float(), reduction="mean")
+
+ if args.motion_sub_loss and noise_pred.size()[1] > 2:
+ gt_sub_noise = noise_pred[:, 1:, :].float() - noise_pred[:, :-1, :].float()
+ pre_sub_noise = target[:, 1:, :].float() - target[:, :-1, :].float()
+ sub_loss = F.mse_loss(gt_sub_noise, pre_sub_noise, reduction="mean")
+ loss = loss * (1 - args.motion_sub_loss_ratio) + sub_loss * args.motion_sub_loss_ratio
+
+ # Gather the losses across all processes for logging (if we use distributed training).
+ avg_loss = accelerator.gather(loss.repeat(args.train_batch_size)).mean()
+ train_loss += avg_loss.item() / args.gradient_accumulation_steps
+
+ # Backpropagate
+ accelerator.backward(loss)
+ if accelerator.sync_gradients:
+ if not args.use_deepspeed:
+ trainable_params_grads = [p.grad for p in trainable_params if p.grad is not None]
+ trainable_params_total_norm = torch.norm(torch.stack([torch.norm(g.detach(), 2) for g in trainable_params_grads]), 2)
+ max_grad_norm = linear_decay(args.max_grad_norm * args.initial_grad_norm_ratio, args.max_grad_norm, args.abnormal_norm_clip_start, global_step)
+ if trainable_params_total_norm / max_grad_norm > 5 and global_step > args.abnormal_norm_clip_start:
+ actual_max_grad_norm = max_grad_norm / min((trainable_params_total_norm / max_grad_norm), 10)
+ else:
+ actual_max_grad_norm = max_grad_norm
+ else:
+ actual_max_grad_norm = args.max_grad_norm
+
+ if not args.use_deepspeed and args.report_model_info and accelerator.is_main_process:
+ if trainable_params_total_norm > 1 and global_step > args.abnormal_norm_clip_start:
+ for name, param in transformer3d.named_parameters():
+ if param.requires_grad:
+ writer.add_scalar(f'gradients/before_clip_norm/{name}', param.grad.norm(), global_step=global_step)
+
+ norm_sum = accelerator.clip_grad_norm_(trainable_params, actual_max_grad_norm)
+ if not args.use_deepspeed and args.report_model_info and accelerator.is_main_process:
+ writer.add_scalar(f'gradients/norm_sum', norm_sum, global_step=global_step)
+ writer.add_scalar(f'gradients/actual_max_grad_norm', actual_max_grad_norm, global_step=global_step)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+
+ if args.use_ema:
+ ema_transformer3d.step(transformer3d.parameters())
+ progress_bar.update(1)
+ global_step += 1
+ accelerator.log({"train_loss": train_loss}, step=global_step)
+ train_loss = 0.0
+
+ if global_step % args.checkpointing_steps == 0:
+ if args.use_deepspeed or accelerator.is_main_process:
+ # _before_ saving state, check if this save would set us over the `checkpoints_total_limit`
+ if args.checkpoints_total_limit is not None:
+ checkpoints = os.listdir(args.output_dir)
+ checkpoints = [d for d in checkpoints if d.startswith("checkpoint")]
+ checkpoints = sorted(checkpoints, key=lambda x: int(x.split("-")[1]))
+
+ # before we save the new checkpoint, we need to have at _most_ `checkpoints_total_limit - 1` checkpoints
+ if len(checkpoints) >= args.checkpoints_total_limit:
+ num_to_remove = len(checkpoints) - args.checkpoints_total_limit + 1
+ removing_checkpoints = checkpoints[0:num_to_remove]
+
+ logger.info(
+ f"{len(checkpoints)} checkpoints already exist, removing {len(removing_checkpoints)} checkpoints"
+ )
+ logger.info(f"removing checkpoints: {', '.join(removing_checkpoints)}")
+
+ for removing_checkpoint in removing_checkpoints:
+ removing_checkpoint = os.path.join(args.output_dir, removing_checkpoint)
+ shutil.rmtree(removing_checkpoint)
+
+ save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
+ accelerator.save_state(save_path)
+ logger.info(f"Saved state to {save_path}")
+
+ if accelerator.is_main_process:
+ if args.validation_prompts is not None and global_step % args.validation_steps == 0:
+ if args.use_ema:
+ # Store the UNet parameters temporarily and load the EMA parameters to perform inference.
+ ema_transformer3d.store(transformer3d.parameters())
+ ema_transformer3d.copy_to(transformer3d.parameters())
+ log_validation(
+ vae,
+ text_encoder,
+ tokenizer,
+ transformer3d,
+ args,
+ accelerator,
+ weight_dtype,
+ global_step,
+ )
+ if args.use_ema:
+ # Switch back to the original transformer3d parameters.
+ ema_transformer3d.restore(transformer3d.parameters())
+
+ logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
+ progress_bar.set_postfix(**logs)
+
+ if global_step >= args.max_train_steps:
+ break
+
+ if accelerator.is_main_process:
+ if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
+ if args.use_ema:
+ # Store the UNet parameters temporarily and load the EMA parameters to perform inference.
+ ema_transformer3d.store(transformer3d.parameters())
+ ema_transformer3d.copy_to(transformer3d.parameters())
+ log_validation(
+ vae,
+ text_encoder,
+ tokenizer,
+ transformer3d,
+ args,
+ accelerator,
+ weight_dtype,
+ global_step,
+ )
+ if args.use_ema:
+ # Switch back to the original transformer3d parameters.
+ ema_transformer3d.restore(transformer3d.parameters())
+
+ # Create the pipeline using the trained modules and save it.
+ accelerator.wait_for_everyone()
+ if accelerator.is_main_process:
+ transformer3d = unwrap_model(transformer3d)
+ if args.use_ema:
+ ema_transformer3d.copy_to(transformer3d.parameters())
+
+ if args.use_deepspeed or accelerator.is_main_process:
+ save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
+ accelerator.save_state(save_path)
+ logger.info(f"Saved state to {save_path}")
+
+ accelerator.end_training()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/scripts/train.sh b/scripts/train.sh
new file mode 100644
index 0000000..ce97428
--- /dev/null
+++ b/scripts/train.sh
@@ -0,0 +1,42 @@
+export MODEL_NAME="models/Diffusion_Transformer/CogVideoX-Fun-2b-InP"
+export DATASET_NAME="datasets/internal_datasets/"
+export DATASET_META_NAME="datasets/internal_datasets/metadata.json"
+export NCCL_IB_DISABLE=1
+export NCCL_P2P_DISABLE=1
+NCCL_DEBUG=INFO
+
+# When train model with multi machines, use "--config_file accelerate.yaml" instead of "--mixed_precision='bf16'".
+accelerate launch --mixed_precision="bf16" scripts/train.py \
+ --pretrained_model_name_or_path=$MODEL_NAME \
+ --train_data_dir=$DATASET_NAME \
+ --train_data_meta=$DATASET_META_NAME \
+ --image_sample_size=1280 \
+ --video_sample_size=256 \
+ --token_sample_size=512 \
+ --video_sample_stride=3 \
+ --video_sample_n_frames=49 \
+ --train_batch_size=1 \
+ --video_repeat=1 \
+ --gradient_accumulation_steps=1 \
+ --dataloader_num_workers=8 \
+ --num_train_epochs=100 \
+ --checkpointing_steps=50 \
+ --learning_rate=2e-05 \
+ --lr_scheduler="constant_with_warmup" \
+ --lr_warmup_steps=100 \
+ --seed=42 \
+ --output_dir="output_dir" \
+ --gradient_checkpointing \
+ --mixed_precision="bf16" \
+ --adam_weight_decay=3e-2 \
+ --adam_epsilon=1e-10 \
+ --vae_mini_batch=1 \
+ --max_grad_norm=0.05 \
+ --random_hw_adapt \
+ --training_with_video_token_length \
+ --random_frame_crop \
+ --enable_bucket \
+ --use_ema \
+ --train_mode="inpaint" \
+ --resume_from_checkpoint="latest" \
+ --trainable_modules "."
\ No newline at end of file
diff --git a/scripts/train_lora.py b/scripts/train_lora.py
new file mode 100644
index 0000000..fb6b4fb
--- /dev/null
+++ b/scripts/train_lora.py
@@ -0,0 +1,1624 @@
+"""Modified from https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image.py
+"""
+#!/usr/bin/env python
+# coding=utf-8
+# Copyright 2024 The HuggingFace Inc. team. All rights reserved.
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+
+import argparse
+import copy
+import gc
+import logging
+import math
+import os
+import pickle
+import shutil
+import sys
+
+import accelerate
+import diffusers
+import numpy as np
+import torch
+import torch.nn.functional as F
+import torch.utils.checkpoint
+import transformers
+from accelerate import Accelerator
+from accelerate.logging import get_logger
+from accelerate.state import AcceleratorState
+from accelerate.utils import ProjectConfiguration, set_seed
+from diffusers import AutoencoderKL, AutoencoderKLCogVideoX, DDPMScheduler
+from diffusers.models.embeddings import get_3d_rotary_pos_embed
+from diffusers.optimization import get_scheduler
+from diffusers.training_utils import EMAModel
+from diffusers.utils import check_min_version, deprecate, is_wandb_available
+from diffusers.utils.import_utils import is_xformers_available
+from diffusers.utils.torch_utils import is_compiled_module
+from einops import rearrange
+from huggingface_hub import create_repo, upload_folder
+from omegaconf import OmegaConf
+from packaging import version
+from PIL import Image
+from torch.utils.data import RandomSampler
+from torch.utils.tensorboard import SummaryWriter
+from torchvision import transforms
+from tqdm.auto import tqdm
+from transformers import (BertModel, BertTokenizer, CLIPImageProcessor,
+ CLIPVisionModelWithProjection, MT5Tokenizer,
+ T5EncoderModel, T5Tokenizer)
+from transformers.utils import ContextManagers
+
+import datasets
+
+current_file_path = os.path.abspath(__file__)
+project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path))]
+for project_root in project_roots:
+ sys.path.insert(0, project_root) if project_root not in sys.path else None
+from cogvideox.data.bucket_sampler import (ASPECT_RATIO_512,
+ ASPECT_RATIO_RANDOM_CROP_512,
+ ASPECT_RATIO_RANDOM_CROP_PROB,
+ AspectRatioBatchImageSampler,
+ AspectRatioBatchImageVideoSampler,
+ AspectRatioBatchSampler,
+ RandomSampler, get_closest_ratio)
+from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_FUN_Pipeline
+from cogvideox.pipeline.pipeline_cogvideox_inpaint import CogVideoX_FUN_Pipeline_Inpaint
+from cogvideox.data.dataset_image import CC15M
+from cogvideox.data.dataset_image_video import (ImageVideoDataset,
+ ImageVideoSampler,
+ get_random_mask)
+from cogvideox.data.dataset_video import VideoDataset, WebVid10M
+from cogvideox.models.transformer3d import CogVideoXTransformer3DModel
+from cogvideox.utils.lora_utils import create_network, merge_lora, unmerge_lora
+from cogvideox.utils.utils import get_image_to_video_latent, save_videos_grid
+
+if is_wandb_available():
+ import wandb
+
+
+def get_random_downsample_ratio(sample_size, image_ratio=[],
+ all_choices=False, rng=None):
+ def _create_special_list(length):
+ if length == 1:
+ return [1.0]
+ if length >= 2:
+ first_element = 0.75
+ remaining_sum = 1.0 - first_element
+ other_elements_value = remaining_sum / (length - 1)
+ special_list = [first_element] + [other_elements_value] * (length - 1)
+ return special_list
+
+ if sample_size >= 1536:
+ number_list = [1, 1.25, 1.5, 2, 2.5, 3] + image_ratio
+ elif sample_size >= 1024:
+ number_list = [1, 1.25, 1.5, 2] + image_ratio
+ elif sample_size >= 768:
+ number_list = [1, 1.25, 1.5] + image_ratio
+ elif sample_size >= 512:
+ number_list = [1] + image_ratio
+ else:
+ number_list = [1]
+
+ if all_choices:
+ return number_list
+
+ number_list_prob = np.array(_create_special_list(len(number_list)))
+ if rng is None:
+ return np.random.choice(number_list, p = number_list_prob)
+ else:
+ return rng.choice(number_list, p = number_list_prob)
+
+def resize_mask(mask, latent, process_first_frame_only=True):
+ latent_size = latent.size()
+ batch_size, channels, num_frames, height, width = mask.shape
+
+ if process_first_frame_only:
+ target_size = list(latent_size[2:])
+ target_size[0] = 1
+ first_frame_resized = F.interpolate(
+ mask[:, :, 0:1, :, :],
+ size=target_size,
+ mode='trilinear',
+ align_corners=False
+ )
+
+ target_size = list(latent_size[2:])
+ target_size[0] = target_size[0] - 1
+ if target_size[0] != 0:
+ remaining_frames_resized = F.interpolate(
+ mask[:, :, 1:, :, :],
+ size=target_size,
+ mode='trilinear',
+ align_corners=False
+ )
+ resized_mask = torch.cat([first_frame_resized, remaining_frames_resized], dim=2)
+ else:
+ resized_mask = first_frame_resized
+ else:
+ target_size = list(latent_size[2:])
+ resized_mask = F.interpolate(
+ mask,
+ size=target_size,
+ mode='trilinear',
+ align_corners=False
+ )
+ return resized_mask
+
+# Will error if the minimal version of diffusers is not installed. Remove at your own risks.
+check_min_version("0.18.0.dev0")
+
+logger = get_logger(__name__, log_level="INFO")
+
+def log_validation(vae, text_encoder, tokenizer, transformer3d, network, args, accelerator, weight_dtype, global_step):
+ try:
+ logger.info("Running validation... ")
+
+ transformer3d_val = CogVideoXTransformer3DModel.from_pretrained_2d(
+ args.pretrained_model_name_or_path, subfolder="transformer",
+ ).to(weight_dtype)
+ transformer3d_val.load_state_dict(accelerator.unwrap_model(transformer3d).state_dict())
+
+ if args.train_mode != "normal":
+ pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
+ args.pretrained_model_name_or_path,
+ vae=accelerator.unwrap_model(vae).to(weight_dtype),
+ text_encoder=accelerator.unwrap_model(text_encoder),
+ tokenizer=tokenizer,
+ transformer=transformer3d_val,
+ torch_dtype=weight_dtype,
+ )
+ else:
+ pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
+ args.pretrained_model_name_or_path,
+ vae=accelerator.unwrap_model(vae).to(weight_dtype),
+ text_encoder=accelerator.unwrap_model(text_encoder),
+ tokenizer=tokenizer,
+ transformer=transformer3d_val,
+ torch_dtype=weight_dtype
+ )
+
+ pipeline = pipeline.to(accelerator.device)
+ pipeline = merge_lora(
+ pipeline, None, 1, accelerator.device, state_dict=accelerator.unwrap_model(network).state_dict(), transformer_only=True
+ )
+
+ if args.seed is None:
+ generator = None
+ else:
+ generator = torch.Generator(device=accelerator.device).manual_seed(args.seed)
+
+ for i in range(len(args.validation_prompts)):
+ with torch.no_grad():
+ if args.train_mode != "normal":
+ with torch.autocast("cuda", dtype=weight_dtype):
+ video_length = int(args.video_sample_n_frames // vae.mini_batch_encoder * vae.mini_batch_encoder) if args.video_sample_n_frames != 1 else 1
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(None, None, video_length=video_length, sample_size=[args.video_sample_size, args.video_sample_size])
+ sample = pipeline(
+ args.validation_prompts[i],
+ video_length = args.video_sample_n_frames,
+ negative_prompt = "bad detailed",
+ height = args.video_sample_size,
+ width = args.video_sample_size,
+ guidance_scale = 7,
+ generator = generator,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ clip_image = clip_image,
+ ).videos
+ os.makedirs(os.path.join(args.output_dir, "sample"), exist_ok=True)
+ save_videos_grid(sample, os.path.join(args.output_dir, f"sample/sample-{global_step}-{i}.gif"))
+
+ video_length = 1
+ input_video, input_video_mask, clip_image = get_image_to_video_latent(None, None, video_length=video_length, sample_size=[args.video_sample_size, args.video_sample_size])
+ sample = pipeline(
+ args.validation_prompts[i],
+ video_length = 1,
+ negative_prompt = "bad detailed",
+ height = args.video_sample_size,
+ width = args.video_sample_size,
+ generator = generator,
+
+ video = input_video,
+ mask_video = input_video_mask,
+ clip_image = clip_image,
+ ).videos
+ os.makedirs(os.path.join(args.output_dir, "sample"), exist_ok=True)
+ save_videos_grid(sample, os.path.join(args.output_dir, f"sample/sample-{global_step}-image-{i}.gif"))
+ else:
+ with torch.autocast("cuda", dtype=weight_dtype):
+ sample = pipeline(
+ args.validation_prompts[i],
+ video_length = args.video_sample_n_frames,
+ negative_prompt = "bad detailed",
+ height = args.video_sample_size,
+ width = args.video_sample_size,
+ generator = generator
+ ).videos
+ os.makedirs(os.path.join(args.output_dir, "sample"), exist_ok=True)
+ save_videos_grid(sample, os.path.join(args.output_dir, f"sample/sample-{global_step}-{i}.gif"))
+
+ sample = pipeline(
+ args.validation_prompts[i],
+ video_length = 1,
+ negative_prompt = "bad detailed",
+ height = args.video_sample_size,
+ width = args.video_sample_size,
+ generator = generator
+ ).videos
+ os.makedirs(os.path.join(args.output_dir, "sample"), exist_ok=True)
+ save_videos_grid(sample, os.path.join(args.output_dir, f"sample/sample-{global_step}-image-{i}.gif"))
+
+ del pipeline
+ del transformer3d_val
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.ipc_collect()
+ except Exception as e:
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.ipc_collect()
+ print(f"Eval error with info {e}")
+ return None
+
+def linear_decay(initial_value, final_value, total_steps, current_step):
+ if current_step >= total_steps:
+ return final_value
+ current_step = max(0, current_step)
+ step_size = (final_value - initial_value) / total_steps
+ current_value = initial_value + step_size * current_step
+ return current_value
+
+def generate_timestep_with_lognorm(low, high, shape, device="cpu", generator=None):
+ u = torch.normal(mean=0.0, std=1.0, size=shape, device=device, generator=generator)
+ t = 1 / (1 + torch.exp(-u)) * (high - low) + low
+ return torch.clip(t.to(torch.int32), low, high - 1)
+
+def parse_args():
+ parser = argparse.ArgumentParser(description="Simple example of a training script.")
+ parser.add_argument(
+ "--input_perturbation", type=float, default=0, help="The scale of input perturbation. Recommended 0.1."
+ )
+ parser.add_argument(
+ "--pretrained_model_name_or_path",
+ type=str,
+ default=None,
+ required=True,
+ help="Path to pretrained model or model identifier from huggingface.co/models.",
+ )
+ parser.add_argument(
+ "--revision",
+ type=str,
+ default=None,
+ required=False,
+ help="Revision of pretrained model identifier from huggingface.co/models.",
+ )
+ parser.add_argument(
+ "--variant",
+ type=str,
+ default=None,
+ help="Variant of the model files of the pretrained model identifier from huggingface.co/models, 'e.g.' fp16",
+ )
+ parser.add_argument(
+ "--train_data_dir",
+ type=str,
+ default=None,
+ help=(
+ "A folder containing the training data. "
+ ),
+ )
+ parser.add_argument(
+ "--train_data_meta",
+ type=str,
+ default=None,
+ help=(
+ "A csv containing the training data. "
+ ),
+ )
+ parser.add_argument(
+ "--max_train_samples",
+ type=int,
+ default=None,
+ help=(
+ "For debugging purposes or quicker training, truncate the number of training examples to this "
+ "value if set."
+ ),
+ )
+ parser.add_argument(
+ "--validation_prompts",
+ type=str,
+ default=None,
+ nargs="+",
+ help=("A set of prompts evaluated every `--validation_epochs` and logged to `--report_to`."),
+ )
+ parser.add_argument(
+ "--output_dir",
+ type=str,
+ default="sd-model-finetuned",
+ help="The output directory where the model predictions and checkpoints will be written.",
+ )
+ parser.add_argument(
+ "--cache_dir",
+ type=str,
+ default=None,
+ help="The directory where the downloaded models and datasets will be stored.",
+ )
+ parser.add_argument("--seed", type=int, default=None, help="A seed for reproducible training.")
+ parser.add_argument(
+ "--random_flip",
+ action="store_true",
+ help="whether to randomly flip images horizontally",
+ )
+ parser.add_argument(
+ "--use_came",
+ action="store_true",
+ help="whether to use came",
+ )
+ parser.add_argument(
+ "--multi_stream",
+ action="store_true",
+ help="whether to use cuda multi-stream",
+ )
+ parser.add_argument(
+ "--train_batch_size", type=int, default=16, help="Batch size (per device) for the training dataloader."
+ )
+ parser.add_argument(
+ "--vae_mini_batch", type=int, default=32, help="mini batch size for vae."
+ )
+ parser.add_argument("--num_train_epochs", type=int, default=100)
+ parser.add_argument(
+ "--max_train_steps",
+ type=int,
+ default=None,
+ help="Total number of training steps to perform. If provided, overrides num_train_epochs.",
+ )
+ parser.add_argument(
+ "--gradient_accumulation_steps",
+ type=int,
+ default=1,
+ help="Number of updates steps to accumulate before performing a backward/update pass.",
+ )
+ parser.add_argument(
+ "--gradient_checkpointing",
+ action="store_true",
+ help="Whether or not to use gradient checkpointing to save memory at the expense of slower backward pass.",
+ )
+ parser.add_argument(
+ "--learning_rate",
+ type=float,
+ default=1e-4,
+ help="Initial learning rate (after the potential warmup period) to use.",
+ )
+ parser.add_argument(
+ "--scale_lr",
+ action="store_true",
+ default=False,
+ help="Scale the learning rate by the number of GPUs, gradient accumulation steps, and batch size.",
+ )
+ parser.add_argument(
+ "--lr_scheduler",
+ type=str,
+ default="constant",
+ help=(
+ 'The scheduler type to use. Choose between ["linear", "cosine", "cosine_with_restarts", "polynomial",'
+ ' "constant", "constant_with_warmup"]'
+ ),
+ )
+ parser.add_argument(
+ "--lr_warmup_steps", type=int, default=500, help="Number of steps for the warmup in the lr scheduler."
+ )
+ parser.add_argument(
+ "--use_8bit_adam", action="store_true", help="Whether or not to use 8-bit Adam from bitsandbytes."
+ )
+ parser.add_argument(
+ "--allow_tf32",
+ action="store_true",
+ help=(
+ "Whether or not to allow TF32 on Ampere GPUs. Can be used to speed up training. For more information, see"
+ " https://pytorch.org/docs/stable/notes/cuda.html#tensorfloat-32-tf32-on-ampere-devices"
+ ),
+ )
+ parser.add_argument("--use_ema", action="store_true", help="Whether to use EMA model.")
+ parser.add_argument(
+ "--non_ema_revision",
+ type=str,
+ default=None,
+ required=False,
+ help=(
+ "Revision of pretrained non-ema model identifier. Must be a branch, tag or git identifier of the local or"
+ " remote repository specified with --pretrained_model_name_or_path."
+ ),
+ )
+ parser.add_argument(
+ "--dataloader_num_workers",
+ type=int,
+ default=0,
+ help=(
+ "Number of subprocesses to use for data loading. 0 means that the data will be loaded in the main process."
+ ),
+ )
+ parser.add_argument("--adam_beta1", type=float, default=0.9, help="The beta1 parameter for the Adam optimizer.")
+ parser.add_argument("--adam_beta2", type=float, default=0.999, help="The beta2 parameter for the Adam optimizer.")
+ parser.add_argument("--adam_weight_decay", type=float, default=1e-2, help="Weight decay to use.")
+ parser.add_argument("--adam_epsilon", type=float, default=1e-08, help="Epsilon value for the Adam optimizer")
+ parser.add_argument("--max_grad_norm", default=1.0, type=float, help="Max gradient norm.")
+ parser.add_argument("--push_to_hub", action="store_true", help="Whether or not to push the model to the Hub.")
+ parser.add_argument("--hub_token", type=str, default=None, help="The token to use to push to the Model Hub.")
+ parser.add_argument(
+ "--prediction_type",
+ type=str,
+ default=None,
+ help="The prediction_type that shall be used for training. Choose between 'epsilon' or 'v_prediction' or leave `None`. If left to `None` the default prediction type of the scheduler: `noise_scheduler.config.prediciton_type` is chosen.",
+ )
+ parser.add_argument(
+ "--hub_model_id",
+ type=str,
+ default=None,
+ help="The name of the repository to keep in sync with the local `output_dir`.",
+ )
+ parser.add_argument(
+ "--logging_dir",
+ type=str,
+ default="logs",
+ help=(
+ "[TensorBoard](https://www.tensorflow.org/tensorboard) log directory. Will default to"
+ " *output_dir/runs/**CURRENT_DATETIME_HOSTNAME***."
+ ),
+ )
+ parser.add_argument(
+ "--mixed_precision",
+ type=str,
+ default=None,
+ choices=["no", "fp16", "bf16"],
+ help=(
+ "Whether to use mixed precision. Choose between fp16 and bf16 (bfloat16). Bf16 requires PyTorch >="
+ " 1.10.and an Nvidia Ampere GPU. Default to the value of accelerate config of the current system or the"
+ " flag passed with the `accelerate.launch` command. Use this argument to override the accelerate config."
+ ),
+ )
+ parser.add_argument(
+ "--report_to",
+ type=str,
+ default="tensorboard",
+ help=(
+ 'The integration to report the results and logs to. Supported platforms are `"tensorboard"`'
+ ' (default), `"wandb"` and `"comet_ml"`. Use `"all"` to report to all integrations.'
+ ),
+ )
+ parser.add_argument("--local_rank", type=int, default=-1, help="For distributed training: local_rank")
+ parser.add_argument(
+ "--checkpointing_steps",
+ type=int,
+ default=500,
+ help=(
+ "Save a checkpoint of the training state every X updates. These checkpoints are only suitable for resuming"
+ " training using `--resume_from_checkpoint`."
+ ),
+ )
+ parser.add_argument(
+ "--checkpoints_total_limit",
+ type=int,
+ default=None,
+ help=("Max number of checkpoints to store."),
+ )
+ parser.add_argument(
+ "--resume_from_checkpoint",
+ type=str,
+ default=None,
+ help=(
+ "Whether training should be resumed from a previous checkpoint. Use a path saved by"
+ ' `--checkpointing_steps`, or `"latest"` to automatically select the last available checkpoint.'
+ ),
+ )
+ parser.add_argument("--noise_offset", type=float, default=0, help="The scale of noise offset.")
+ parser.add_argument(
+ "--validation_epochs",
+ type=int,
+ default=5,
+ help="Run validation every X epochs.",
+ )
+ parser.add_argument(
+ "--validation_steps",
+ type=int,
+ default=2000,
+ help="Run validation every X steps.",
+ )
+ parser.add_argument(
+ "--tracker_project_name",
+ type=str,
+ default="text2image-fine-tune",
+ help=(
+ "The `project_name` argument passed to Accelerator.init_trackers for"
+ " more information see https://huggingface.co/docs/accelerate/v0.17.0/en/package_reference/accelerator#accelerate.Accelerator"
+ ),
+ )
+
+ parser.add_argument(
+ "--rank",
+ type=int,
+ default=128,
+ help=("The dimension of the LoRA update matrices."),
+ )
+ parser.add_argument(
+ "--network_alpha",
+ type=int,
+ default=64,
+ help=("The dimension of the LoRA update matrices."),
+ )
+ parser.add_argument(
+ "--train_text_encoder",
+ action="store_true",
+ help="Whether to train the text encoder. If set, the text encoder should be float32 precision.",
+ )
+ parser.add_argument(
+ "--snr_loss", action="store_true", help="Whether or not to use snr_loss."
+ )
+ parser.add_argument(
+ "--enable_text_encoder_in_dataloader", action="store_true", help="Whether or not to use text encoder in dataloader."
+ )
+ parser.add_argument(
+ "--enable_bucket", action="store_true", help="Whether enable bucket sample in datasets."
+ )
+ parser.add_argument(
+ "--random_ratio_crop", action="store_true", help="Whether enable random ratio crop sample in datasets."
+ )
+ parser.add_argument(
+ "--random_frame_crop", action="store_true", help="Whether enable random frame crop sample in datasets."
+ )
+ parser.add_argument(
+ "--random_hw_adapt", action="store_true", help="Whether enable random adapt height and width in datasets."
+ )
+ parser.add_argument(
+ "--training_with_video_token_length", action="store_true", help="The training stage of the model in training.",
+ )
+ parser.add_argument(
+ "--noise_share_in_frames", action="store_true", help="Whether enable noise share in frames."
+ )
+ parser.add_argument(
+ "--noise_share_in_frames_ratio", type=float, default=0.5, help="Noise share ratio.",
+ )
+ parser.add_argument(
+ "--motion_sub_loss", action="store_true", help="Whether enable motion sub loss."
+ )
+ parser.add_argument(
+ "--motion_sub_loss_ratio", type=float, default=0.25, help="The ratio of motion sub loss."
+ )
+ parser.add_argument(
+ "--keep_all_node_same_token_length",
+ action="store_true",
+ help="Reference of the length token.",
+ )
+ parser.add_argument(
+ "--train_sampling_steps",
+ type=int,
+ default=1000,
+ help="Run train_sampling_steps.",
+ )
+ parser.add_argument(
+ "--token_sample_size",
+ type=int,
+ default=512,
+ help="Sample size of the token.",
+ )
+ parser.add_argument(
+ "--video_sample_size",
+ type=int,
+ default=512,
+ help="Sample size of the video.",
+ )
+ parser.add_argument(
+ "--image_sample_size",
+ type=int,
+ default=512,
+ help="Sample size of the video.",
+ )
+ parser.add_argument(
+ "--video_sample_stride",
+ type=int,
+ default=4,
+ help="Sample stride of the video.",
+ )
+ parser.add_argument(
+ "--video_sample_n_frames",
+ type=int,
+ default=17,
+ help="Num frame of video.",
+ )
+ parser.add_argument(
+ "--video_repeat",
+ type=int,
+ default=0,
+ help="Num of repeat video.",
+ )
+ parser.add_argument(
+ "--image_repeat_in_forward",
+ type=int,
+ default=0,
+ help="Num of repeat image in forward.",
+ )
+ parser.add_argument(
+ "--transformer_path",
+ type=str,
+ default=None,
+ help=("If you want to load the weight from other transformers, input its path."),
+ )
+ parser.add_argument(
+ "--vae_path",
+ type=str,
+ default=None,
+ help=("If you want to load the weight from other vaes, input its path."),
+ )
+ parser.add_argument("--save_state", action="store_true", help="Whether or not to save state.")
+
+ parser.add_argument(
+ '--tokenizer_max_length',
+ type=int,
+ default=226,
+ help='Max length of tokenizer'
+ )
+ parser.add_argument(
+ "--use_deepspeed", action="store_true", help="Whether or not to use deepspeed."
+ )
+ parser.add_argument(
+ "--low_vram", action="store_true", help="Whether enable low_vram mode."
+ )
+ parser.add_argument(
+ "--train_mode",
+ type=str,
+ default="normal",
+ help=(
+ 'The format of training data. Support `"normal"`'
+ ' (default), `"inpaint"`.'
+ ),
+ )
+
+ args = parser.parse_args()
+ env_local_rank = int(os.environ.get("LOCAL_RANK", -1))
+ if env_local_rank != -1 and env_local_rank != args.local_rank:
+ args.local_rank = env_local_rank
+
+ # default to using the same revision for the non-ema model if not specified
+ if args.non_ema_revision is None:
+ args.non_ema_revision = args.revision
+
+ return args
+
+
+def main():
+ args = parse_args()
+
+ if args.report_to == "wandb" and args.hub_token is not None:
+ raise ValueError(
+ "You cannot use both --report_to=wandb and --hub_token due to a security risk of exposing your token."
+ " Please use `huggingface-cli login` to authenticate with the Hub."
+ )
+
+ if args.non_ema_revision is not None:
+ deprecate(
+ "non_ema_revision!=None",
+ "0.15.0",
+ message=(
+ "Downloading 'non_ema' weights from revision branches of the Hub is deprecated. Please make sure to"
+ " use `--variant=non_ema` instead."
+ ),
+ )
+ logging_dir = os.path.join(args.output_dir, args.logging_dir)
+
+ accelerator_project_config = ProjectConfiguration(project_dir=args.output_dir, logging_dir=logging_dir)
+
+ accelerator = Accelerator(
+ gradient_accumulation_steps=args.gradient_accumulation_steps,
+ mixed_precision=args.mixed_precision,
+ log_with=args.report_to,
+ project_config=accelerator_project_config,
+ )
+ if accelerator.is_main_process:
+ writer = SummaryWriter(log_dir=logging_dir)
+
+ # Make one log on every process with the configuration for debugging.
+ logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ level=logging.INFO,
+ )
+ logger.info(accelerator.state, main_process_only=False)
+ if accelerator.is_local_main_process:
+ datasets.utils.logging.set_verbosity_warning()
+ transformers.utils.logging.set_verbosity_warning()
+ diffusers.utils.logging.set_verbosity_info()
+ else:
+ datasets.utils.logging.set_verbosity_error()
+ transformers.utils.logging.set_verbosity_error()
+ diffusers.utils.logging.set_verbosity_error()
+
+ # If passed along, set the training seed now.
+ if args.seed is not None:
+ set_seed(args.seed)
+ rng = np.random.default_rng(np.random.PCG64(args.seed + accelerator.process_index))
+ torch_rng = torch.Generator(accelerator.device).manual_seed(args.seed + accelerator.process_index)
+ else:
+ rng = None
+ torch_rng = None
+ index_rng = np.random.default_rng(np.random.PCG64(43))
+ print(f"Init rng with seed {args.seed + accelerator.process_index}. Process_index is {accelerator.process_index}")
+
+ # Handle the repository creation
+ if accelerator.is_main_process:
+ if args.output_dir is not None:
+ os.makedirs(args.output_dir, exist_ok=True)
+
+ # For mixed precision training we cast all non-trainable weigths (vae, non-lora text_encoder and non-lora transformer3d) to half-precision
+ # as these weights are only used for inference, keeping weights in full precision is not required.
+ weight_dtype = torch.float32
+ if accelerator.mixed_precision == "fp16":
+ weight_dtype = torch.float16
+ args.mixed_precision = accelerator.mixed_precision
+ elif accelerator.mixed_precision == "bf16":
+ weight_dtype = torch.bfloat16
+ args.mixed_precision = accelerator.mixed_precision
+
+ # Load scheduler, tokenizer and models.
+ noise_scheduler = DDPMScheduler.from_pretrained(args.pretrained_model_name_or_path, subfolder="scheduler")
+
+ tokenizer = T5Tokenizer.from_pretrained(
+ args.pretrained_model_name_or_path, subfolder="tokenizer", revision=args.revision
+ )
+
+ def deepspeed_zero_init_disabled_context_manager():
+ """
+ returns either a context list that includes one that will disable zero.Init or an empty context list
+ """
+ deepspeed_plugin = AcceleratorState().deepspeed_plugin if accelerate.state.is_initialized() else None
+ if deepspeed_plugin is None:
+ return []
+
+ return [deepspeed_plugin.zero3_init_context_manager(enable=False)]
+
+ # Currently Accelerate doesn't know how to handle multiple models under Deepspeed ZeRO stage 3.
+ # For this to work properly all models must be run through `accelerate.prepare`. But accelerate
+ # will try to assign the same optimizer with the same weights to all models during
+ # `deepspeed.initialize`, which of course doesn't work.
+ #
+ # For now the following workaround will partially support Deepspeed ZeRO-3, by excluding the 2
+ # frozen models from being partitioned during `zero.Init` which gets called during
+ # `from_pretrained` So CLIPTextModel and AutoencoderKL will not enjoy the parameter sharding
+ # across multiple gpus and only UNet2DConditionModel will get ZeRO sharded.
+ with ContextManagers(deepspeed_zero_init_disabled_context_manager()):
+ text_encoder = T5EncoderModel.from_pretrained(
+ args.pretrained_model_name_or_path, subfolder="text_encoder", revision=args.revision, variant=args.variant,
+ torch_dtype=weight_dtype
+ )
+
+ vae = AutoencoderKLCogVideoX.from_pretrained(
+ args.pretrained_model_name_or_path, subfolder="vae", revision=args.revision, variant=args.variant
+ )
+
+ transformer3d = CogVideoXTransformer3DModel.from_pretrained_2d(
+ args.pretrained_model_name_or_path, subfolder="transformer"
+ )
+
+ # Freeze vae and text_encoder and set transformer3d to trainable
+ vae.requires_grad_(False)
+ text_encoder.requires_grad_(False)
+ transformer3d.requires_grad_(False)
+
+ # Lora will work with this...
+ network = create_network(
+ 1.0,
+ args.rank,
+ args.network_alpha,
+ text_encoder,
+ transformer3d,
+ neuron_dropout=None,
+ add_lora_in_attn_temporal=True,
+ )
+ network.apply_to(text_encoder, transformer3d, args.train_text_encoder and not args.training_with_video_token_length, True)
+
+ if args.transformer_path is not None:
+ print(f"From checkpoint: {args.transformer_path}")
+ if args.transformer_path.endswith("safetensors"):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(args.transformer_path)
+ else:
+ state_dict = torch.load(args.transformer_path, map_location="cpu")
+ state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
+
+ m, u = transformer3d.load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+ assert len(u) == 0
+
+ if args.vae_path is not None:
+ print(f"From checkpoint: {args.vae_path}")
+ if args.vae_path.endswith("safetensors"):
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(args.vae_path)
+ else:
+ state_dict = torch.load(args.vae_path, map_location="cpu")
+ state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
+
+ m, u = vae.load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+ assert len(u) == 0
+
+ # `accelerate` 0.16.0 will have better support for customized saving
+ if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
+ # create custom saving & loading hooks so that `accelerator.save_state(...)` serializes in a nice format
+ def save_model_hook(models, weights, output_dir):
+ if accelerator.is_main_process:
+ safetensor_save_path = os.path.join(output_dir, f"lora_diffusion_pytorch_model.safetensors")
+ save_model(safetensor_save_path, accelerator.unwrap_model(models[-1]))
+ if not args.use_deepspeed:
+ for _ in range(len(weights)):
+ weights.pop()
+
+ with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
+ pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
+
+ def load_model_hook(models, input_dir):
+ pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
+ if os.path.exists(pkl_path):
+ with open(pkl_path, 'rb') as file:
+ loaded_number, _ = pickle.load(file)
+ batch_sampler.sampler._pos_start = max(loaded_number - args.dataloader_num_workers * accelerator.num_processes * 2, 0)
+ print(f"Load pkl from {pkl_path}. Get loaded_number = {loaded_number}.")
+
+ accelerator.register_save_state_pre_hook(save_model_hook)
+ accelerator.register_load_state_pre_hook(load_model_hook)
+
+ if args.gradient_checkpointing:
+ transformer3d.enable_gradient_checkpointing()
+
+ # Enable TF32 for faster training on Ampere GPUs,
+ # cf https://pytorch.org/docs/stable/notes/cuda.html#tensorfloat-32-tf32-on-ampere-devices
+ if args.allow_tf32:
+ torch.backends.cuda.matmul.allow_tf32 = True
+
+ if args.scale_lr:
+ args.learning_rate = (
+ args.learning_rate * args.gradient_accumulation_steps * args.train_batch_size * accelerator.num_processes
+ )
+
+ # Initialize the optimizer
+ if args.use_8bit_adam:
+ try:
+ import bitsandbytes as bnb
+ except ImportError:
+ raise ImportError(
+ "Please install bitsandbytes to use 8-bit Adam. You can do so by running `pip install bitsandbytes`"
+ )
+
+ optimizer_cls = bnb.optim.AdamW8bit
+ elif args.use_came:
+ try:
+ from came_pytorch import CAME
+ except:
+ raise ImportError(
+ "Please install came_pytorch to use CAME. You can do so by running `pip install came_pytorch`"
+ )
+
+ optimizer_cls = CAME
+ else:
+ optimizer_cls = torch.optim.AdamW
+
+ logging.info("Add network parameters")
+ trainable_params = list(filter(lambda p: p.requires_grad, network.parameters()))
+ trainable_params_optim = network.prepare_optimizer_params(args.learning_rate / 2, args.learning_rate, args.learning_rate)
+
+ if args.use_came:
+ optimizer = optimizer_cls(
+ trainable_params_optim,
+ lr=args.learning_rate,
+ # weight_decay=args.adam_weight_decay,
+ betas=(0.9, 0.999, 0.9999),
+ eps=(1e-30, 1e-16)
+ )
+ else:
+ optimizer = optimizer_cls(
+ trainable_params_optim,
+ lr=args.learning_rate,
+ betas=(args.adam_beta1, args.adam_beta2),
+ weight_decay=args.adam_weight_decay,
+ eps=args.adam_epsilon,
+ )
+
+ # Get the training dataset
+ sample_n_frames_bucket_interval = 4
+
+ train_dataset = ImageVideoDataset(
+ args.train_data_meta, args.train_data_dir,
+ video_sample_size=args.video_sample_size, video_sample_stride=args.video_sample_stride, video_sample_n_frames=args.video_sample_n_frames,
+ video_repeat=args.video_repeat,
+ image_sample_size=args.image_sample_size,
+ enable_bucket=args.enable_bucket, enable_inpaint=True if args.train_mode != "normal" else False,
+ )
+
+ if args.enable_bucket:
+ aspect_ratio_sample_size = {key : [x / 512 * args.video_sample_size for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ aspect_ratio_random_crop_sample_size = {key : [x / 512 * args.video_sample_size for x in ASPECT_RATIO_RANDOM_CROP_512[key]] for key in ASPECT_RATIO_RANDOM_CROP_512.keys()}
+
+ batch_sampler_generator = torch.Generator().manual_seed(args.seed)
+ batch_sampler = AspectRatioBatchImageVideoSampler(
+ sampler=RandomSampler(train_dataset, generator=batch_sampler_generator), dataset=train_dataset.dataset,
+ batch_size=args.train_batch_size, train_folder = args.train_data_dir, drop_last=True,
+ aspect_ratios=aspect_ratio_sample_size,
+ )
+ if args.keep_all_node_same_token_length:
+ if args.token_sample_size > 256:
+ numbers_list = list(range(256, args.token_sample_size + 1, 128))
+
+ if numbers_list[-1] != args.token_sample_size:
+ numbers_list.append(args.token_sample_size)
+ else:
+ numbers_list = [256]
+ numbers_list = [_number * _number * args.video_sample_n_frames for _number in numbers_list]
+ else:
+ numbers_list = None
+
+ def get_length_to_frame_num(token_length):
+ if args.image_sample_size > args.video_sample_size:
+ sample_sizes = list(range(256, args.image_sample_size + 1, 128))
+
+ if sample_sizes[-1] != args.image_sample_size:
+ sample_sizes.append(args.image_sample_size)
+ else:
+ sample_sizes = [256]
+
+ length_to_frame_num = {
+ sample_size: min(token_length / sample_size / sample_size, args.video_sample_n_frames) // sample_n_frames_bucket_interval * sample_n_frames_bucket_interval + 1 for sample_size in sample_sizes
+ }
+
+ return length_to_frame_num
+
+ def collate_fn(examples):
+ target_token_length = args.video_sample_n_frames * args.token_sample_size * args.token_sample_size
+ length_to_frame_num = get_length_to_frame_num(
+ target_token_length,
+ )
+
+ # Create new output
+ new_examples = {}
+ new_examples["target_token_length"] = target_token_length
+ new_examples["pixel_values"] = []
+ new_examples["text"] = []
+ if args.train_mode != "normal":
+ new_examples["mask_pixel_values"] = []
+ new_examples["mask"] = []
+
+ # Get ratio
+ pixel_value = examples[0]["pixel_values"]
+ data_type = examples[0]["data_type"]
+ f, h, w, c = np.shape(pixel_value)
+ if data_type == 'image':
+ random_downsample_ratio = 1 if not args.random_hw_adapt else get_random_downsample_ratio(args.image_sample_size, image_ratio=[args.image_sample_size / args.video_sample_size], rng=rng)
+
+ aspect_ratio_sample_size = {key : [x / 512 * args.image_sample_size / random_downsample_ratio for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ aspect_ratio_random_crop_sample_size = {key : [x / 512 * args.image_sample_size / random_downsample_ratio for x in ASPECT_RATIO_RANDOM_CROP_512[key]] for key in ASPECT_RATIO_RANDOM_CROP_512.keys()}
+
+ batch_video_length = args.video_sample_n_frames + sample_n_frames_bucket_interval
+ else:
+ if args.random_hw_adapt:
+ if args.training_with_video_token_length:
+ local_min_size = np.min(np.array([np.mean(np.array([np.shape(example["pixel_values"])[1], np.shape(example["pixel_values"])[2]])) for example in examples]))
+ choice_list = [length for length in list(length_to_frame_num.keys()) if length < local_min_size * 1.25]
+ if len(choice_list) == 0:
+ choice_list = list(length_to_frame_num.keys())
+ if rng is None:
+ local_video_sample_size = np.random.choice(choice_list)
+ else:
+ local_video_sample_size = rng.choice(choice_list)
+ batch_video_length = length_to_frame_num[local_video_sample_size]
+ random_downsample_ratio = args.video_sample_size / local_video_sample_size
+ else:
+ random_downsample_ratio = get_random_downsample_ratio(
+ args.video_sample_size, rng=rng)
+ batch_video_length = args.video_sample_n_frames + sample_n_frames_bucket_interval
+ else:
+ random_downsample_ratio = 1
+ batch_video_length = args.video_sample_n_frames + sample_n_frames_bucket_interval
+
+ aspect_ratio_sample_size = {key : [x / 512 * args.video_sample_size / random_downsample_ratio for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
+ aspect_ratio_random_crop_sample_size = {key : [x / 512 * args.video_sample_size / random_downsample_ratio for x in ASPECT_RATIO_RANDOM_CROP_512[key]] for key in ASPECT_RATIO_RANDOM_CROP_512.keys()}
+
+ closest_size, closest_ratio = get_closest_ratio(h, w, ratios=aspect_ratio_sample_size)
+ closest_size = [int(x / 16) * 16 for x in closest_size]
+ if args.random_ratio_crop:
+ if rng is None:
+ random_sample_size = aspect_ratio_random_crop_sample_size[
+ np.random.choice(list(aspect_ratio_random_crop_sample_size.keys()), p = ASPECT_RATIO_RANDOM_CROP_PROB)
+ ]
+ else:
+ random_sample_size = aspect_ratio_random_crop_sample_size[
+ rng.choice(list(aspect_ratio_random_crop_sample_size.keys()), p = ASPECT_RATIO_RANDOM_CROP_PROB)
+ ]
+ random_sample_size = [int(x / 16) * 16 for x in random_sample_size]
+
+ for example in examples:
+ if args.random_ratio_crop:
+ # To 0~1
+ pixel_values = torch.from_numpy(example["pixel_values"]).permute(0, 3, 1, 2).contiguous()
+ pixel_values = pixel_values / 255.
+
+ # Get adapt hw for resize
+ b, c, h, w = pixel_values.size()
+ th, tw = random_sample_size
+ if th / tw > h / w:
+ nh = int(th)
+ nw = int(w / h * nh)
+ else:
+ nw = int(tw)
+ nh = int(h / w * nw)
+
+ transform = transforms.Compose([
+ transforms.Resize([nh, nw]),
+ transforms.CenterCrop([int(x) for x in random_sample_size]),
+ transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
+ ])
+ else:
+ closest_size = list(map(lambda x: int(x), closest_size))
+ if closest_size[0] / h > closest_size[1] / w:
+ resize_size = closest_size[0], int(w * closest_size[0] / h)
+ else:
+ resize_size = int(h * closest_size[1] / w), closest_size[1]
+
+ pixel_values = torch.from_numpy(example["pixel_values"]).permute(0, 3, 1, 2).contiguous()
+ pixel_values = pixel_values / 255.
+ transform = transforms.Compose([
+ transforms.Resize(resize_size, interpolation=transforms.InterpolationMode.BILINEAR), # Image.BICUBIC
+ transforms.CenterCrop(closest_size),
+ transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
+ ])
+ new_examples["pixel_values"].append(transform(pixel_values))
+ new_examples["text"].append(example["text"])
+ batch_video_length = int(
+ min(
+ batch_video_length,
+ (len(pixel_values) - 1) // sample_n_frames_bucket_interval * sample_n_frames_bucket_interval + 1,
+ )
+ )
+
+ if batch_video_length == 0:
+ batch_video_length = 1
+
+ if args.train_mode != "normal":
+ mask = get_random_mask(new_examples["pixel_values"][-1].size())
+ mask_pixel_values = new_examples["pixel_values"][-1] * (1 - mask) + torch.ones_like(new_examples["pixel_values"][-1]) * -1 * mask
+ new_examples["mask_pixel_values"].append(mask_pixel_values)
+ new_examples["mask"].append(mask)
+
+ new_examples["pixel_values"] = torch.stack([example[:batch_video_length] for example in new_examples["pixel_values"]])
+ if args.train_mode != "normal":
+ new_examples["mask_pixel_values"] = torch.stack([example[:batch_video_length] for example in new_examples["mask_pixel_values"]])
+ new_examples["mask"] = torch.stack([example[:batch_video_length] for example in new_examples["mask"]])
+
+ if args.enable_text_encoder_in_dataloader:
+ prompt_ids = tokenizer(
+ new_examples['text'],
+ max_length=args.tokenizer_max_length,
+ padding="max_length",
+ add_special_tokens=True,
+ truncation=True,
+ return_tensors="pt"
+ )
+ encoder_hidden_states = text_encoder(
+ prompt_ids.input_ids,
+ return_dict=False
+ )[0]
+ new_examples['encoder_attention_mask'] = prompt_ids.attention_mask
+ new_examples['encoder_hidden_states'] = encoder_hidden_states
+
+ return new_examples
+
+ # DataLoaders creation:
+ train_dataloader = torch.utils.data.DataLoader(
+ train_dataset,
+ batch_sampler=batch_sampler,
+ collate_fn=collate_fn,
+ persistent_workers=True if args.dataloader_num_workers != 0 else False,
+ num_workers=args.dataloader_num_workers,
+ )
+ else:
+ # DataLoaders creation:
+ batch_sampler_generator = torch.Generator().manual_seed(args.seed)
+ batch_sampler = ImageVideoSampler(RandomSampler(train_dataset, generator=batch_sampler_generator), train_dataset, args.train_batch_size)
+ train_dataloader = torch.utils.data.DataLoader(
+ train_dataset,
+ batch_sampler=batch_sampler,
+ persistent_workers=True if args.dataloader_num_workers != 0 else False,
+ num_workers=args.dataloader_num_workers,
+ )
+
+ # Scheduler and math around the number of training steps.
+ overrode_max_train_steps = False
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if args.max_train_steps is None:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ overrode_max_train_steps = True
+
+ lr_scheduler = get_scheduler(
+ args.lr_scheduler,
+ optimizer=optimizer,
+ num_warmup_steps=args.lr_warmup_steps * accelerator.num_processes,
+ num_training_steps=args.max_train_steps * accelerator.num_processes,
+ )
+
+ # Prepare everything with our `accelerator`.
+ network, optimizer, train_dataloader, lr_scheduler = accelerator.prepare(
+ network, optimizer, train_dataloader, lr_scheduler
+ )
+
+ # Move text_encode and vae to gpu and cast to weight_dtype
+ vae.to(accelerator.device, dtype=weight_dtype)
+ transformer3d.to(accelerator.device, dtype=weight_dtype)
+ if not args.enable_text_encoder_in_dataloader:
+ text_encoder.to(accelerator.device)
+
+ # We need to recalculate our total training steps as the size of the training dataloader may have changed.
+ num_update_steps_per_epoch = math.ceil(len(train_dataloader) / args.gradient_accumulation_steps)
+ if overrode_max_train_steps:
+ args.max_train_steps = args.num_train_epochs * num_update_steps_per_epoch
+ # Afterwards we recalculate our number of training epochs
+ args.num_train_epochs = math.ceil(args.max_train_steps / num_update_steps_per_epoch)
+
+ # We need to initialize the trackers we use, and also store our configuration.
+ # The trackers initializes automatically on the main process.
+ if accelerator.is_main_process:
+ tracker_config = dict(vars(args))
+ tracker_config.pop("validation_prompts")
+ accelerator.init_trackers(args.tracker_project_name, tracker_config)
+
+ # Function for unwrapping if model was compiled with `torch.compile`.
+ def unwrap_model(model):
+ model = accelerator.unwrap_model(model)
+ model = model._orig_mod if is_compiled_module(model) else model
+ return model
+
+ # Train!
+ total_batch_size = args.train_batch_size * accelerator.num_processes * args.gradient_accumulation_steps
+
+ logger.info("***** Running training *****")
+ logger.info(f" Num examples = {len(train_dataset)}")
+ logger.info(f" Num Epochs = {args.num_train_epochs}")
+ logger.info(f" Instantaneous batch size per device = {args.train_batch_size}")
+ logger.info(f" Total train batch size (w. parallel, distributed & accumulation) = {total_batch_size}")
+ logger.info(f" Gradient Accumulation steps = {args.gradient_accumulation_steps}")
+ logger.info(f" Total optimization steps = {args.max_train_steps}")
+ global_step = 0
+ first_epoch = 0
+
+ # Potentially load in the weights and states from a previous save
+ if args.resume_from_checkpoint:
+ if args.resume_from_checkpoint != "latest":
+ path = os.path.basename(args.resume_from_checkpoint)
+ else:
+ # Get the most recent checkpoint
+ dirs = os.listdir(args.output_dir)
+ dirs = [d for d in dirs if d.startswith("checkpoint")]
+ dirs = sorted(dirs, key=lambda x: int(x.split("-")[1]))
+ path = dirs[-1] if len(dirs) > 0 else None
+
+ if path is None:
+ accelerator.print(
+ f"Checkpoint '{args.resume_from_checkpoint}' does not exist. Starting a new training run."
+ )
+ args.resume_from_checkpoint = None
+ initial_global_step = 0
+ else:
+ global_step = int(path.split("-")[1])
+
+ initial_global_step = global_step
+
+ pkl_path = os.path.join(os.path.join(args.output_dir, path), "sampler_pos_start.pkl")
+ if os.path.exists(pkl_path):
+ with open(pkl_path, 'rb') as file:
+ _, first_epoch = pickle.load(file)
+ else:
+ first_epoch = global_step // num_update_steps_per_epoch
+ print(f"Load pkl from {pkl_path}. Get first_epoch = {first_epoch}.")
+
+ from safetensors.torch import load_file, safe_open
+ state_dict = load_file(os.path.join(os.path.join(args.output_dir, path), "lora_diffusion_pytorch_model.safetensors"))
+ m, u = accelerator.unwrap_model(network).load_state_dict(state_dict, strict=False)
+ print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
+
+ accelerator.print(f"Resuming from checkpoint {path}")
+ accelerator.load_state(os.path.join(args.output_dir, path))
+ else:
+ initial_global_step = 0
+
+ # function for saving/removing
+ def save_model(ckpt_file, unwrapped_nw):
+ os.makedirs(args.output_dir, exist_ok=True)
+ accelerator.print(f"\nsaving checkpoint: {ckpt_file}")
+ unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
+
+ progress_bar = tqdm(
+ range(0, args.max_train_steps),
+ initial=initial_global_step,
+ desc="Steps",
+ # Only show the progress bar once on each machine.
+ disable=not accelerator.is_local_main_process,
+ )
+
+ if args.multi_stream and args.train_mode != "normal":
+ # create extra cuda streams to speedup inpaint vae computation
+ vae_stream_1 = torch.cuda.Stream()
+ vae_stream_2 = torch.cuda.Stream()
+ else:
+ vae_stream_1 = None
+ vae_stream_2 = None
+
+ for epoch in range(first_epoch, args.num_train_epochs):
+ train_loss = 0.0
+ batch_sampler.sampler.generator = torch.Generator().manual_seed(args.seed + epoch)
+ for step, batch in enumerate(train_dataloader):
+ # Data batch sanity check
+ if epoch == first_epoch and step == 0:
+ pixel_values, texts = batch['pixel_values'].cpu(), batch['text']
+ pixel_values = rearrange(pixel_values, "b f c h w -> b c f h w")
+ os.makedirs(os.path.join(args.output_dir, "sanity_check"), exist_ok=True)
+ for idx, (pixel_value, text) in enumerate(zip(pixel_values, texts)):
+ pixel_value = pixel_value[None, ...]
+ gif_name = '-'.join(text.replace('/', '').split()[:10]) if not text == '' else f'{global_step}-{idx}'
+ save_videos_grid(pixel_value, f"{args.output_dir}/sanity_check/{gif_name[:10]}.gif", rescale=True)
+ if args.train_mode != "normal":
+ mask_pixel_values, texts = batch['mask_pixel_values'].cpu(), batch['text']
+ mask_pixel_values = rearrange(mask_pixel_values, "b f c h w -> b c f h w")
+ for idx, (pixel_value, text) in enumerate(zip(mask_pixel_values, texts)):
+ pixel_value = pixel_value[None, ...]
+ save_videos_grid(pixel_value, f"{args.output_dir}/sanity_check/mask_{gif_name[:10] if not text == '' else f'{global_step}-{idx}'}.gif", rescale=True)
+
+ with accelerator.accumulate(transformer3d):
+ # Convert images to latent space
+ pixel_values = batch["pixel_values"].to(weight_dtype)
+ if args.training_with_video_token_length:
+ if args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 16 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
+ pixel_values = torch.tile(pixel_values, (4, 1, 1, 1, 1))
+ if args.enable_text_encoder_in_dataloader:
+ batch['encoder_hidden_states'] = torch.tile(batch['encoder_hidden_states'], (4, 1, 1))
+ batch['encoder_attention_mask'] = torch.tile(batch['encoder_attention_mask'], (4, 1))
+ else:
+ batch['text'] = batch['text'] * 4
+ elif args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 4 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
+ pixel_values = torch.tile(pixel_values, (2, 1, 1, 1, 1))
+ if args.enable_text_encoder_in_dataloader:
+ batch['encoder_hidden_states'] = torch.tile(batch['encoder_hidden_states'], (2, 1, 1))
+ batch['encoder_attention_mask'] = torch.tile(batch['encoder_attention_mask'], (2, 1))
+ else:
+ batch['text'] = batch['text'] * 2
+
+ if args.train_mode != "normal":
+ mask_pixel_values = batch["mask_pixel_values"].to(weight_dtype)
+ mask = batch["mask"].to(weight_dtype)
+ if args.training_with_video_token_length:
+ if args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 16 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
+ mask_pixel_values = torch.tile(mask_pixel_values, (4, 1, 1, 1, 1))
+ mask = torch.tile(mask, (4, 1, 1, 1, 1))
+ elif args.video_sample_n_frames * args.token_sample_size * args.token_sample_size // 4 >= pixel_values.size()[1] * pixel_values.size()[3] * pixel_values.size()[4]:
+ mask_pixel_values = torch.tile(mask_pixel_values, (2, 1, 1, 1, 1))
+ mask = torch.tile(mask, (2, 1, 1, 1, 1))
+
+ def create_special_list(length):
+ if length == 1:
+ return [1.0]
+ if length >= 2:
+ last_element = 0.90
+ remaining_sum = 1.0 - last_element
+ other_elements_value = remaining_sum / (length - 1)
+ special_list = [other_elements_value] * (length - 1) + [last_element]
+ return special_list
+
+ if args.keep_all_node_same_token_length:
+ actual_token_length = index_rng.choice(numbers_list)
+
+ actual_video_length = (min(
+ actual_token_length / pixel_values.size()[-1] / pixel_values.size()[-2], args.video_sample_n_frames
+ ) - 1) // sample_n_frames_bucket_interval * sample_n_frames_bucket_interval + 1
+ actual_video_length = int(max(actual_video_length, 1))
+ else:
+ actual_video_length = None
+
+ if args.random_frame_crop:
+ select_frames = [_tmp for _tmp in list(range(sample_n_frames_bucket_interval + 1, args.video_sample_n_frames + sample_n_frames_bucket_interval, sample_n_frames_bucket_interval))]
+ select_frames_prob = np.array(create_special_list(len(select_frames)))
+
+ if rng is None:
+ temp_n_frames = np.random.choice(select_frames, p = select_frames_prob)
+ else:
+ temp_n_frames = rng.choice(select_frames, p = select_frames_prob)
+ if args.keep_all_node_same_token_length:
+ temp_n_frames = min(actual_video_length, temp_n_frames)
+
+ pixel_values = pixel_values[:, :temp_n_frames, :, :]
+
+ if args.train_mode != "normal":
+ mask_pixel_values = mask_pixel_values[:, :temp_n_frames, :, :]
+ mask = mask[:, :temp_n_frames, :, :]
+
+ if args.train_mode != "normal":
+ t2v_flag = [(_mask == 1).all() for _mask in mask]
+ new_t2v_flag = []
+ for _mask in t2v_flag:
+ if _mask and np.random.rand() < 0.90:
+ new_t2v_flag.append(0)
+ else:
+ new_t2v_flag.append(1)
+ t2v_flag = torch.from_numpy(np.array(new_t2v_flag)).to(accelerator.device, dtype=weight_dtype)
+
+ if args.low_vram:
+ torch.cuda.empty_cache()
+ vae.to(accelerator.device)
+ if not args.enable_text_encoder_in_dataloader:
+ text_encoder.to("cpu")
+
+ with torch.no_grad():
+ # This way is quicker when batch grows up
+ def _slice_vae(pixel_values):
+ pixel_values = rearrange(pixel_values, "b f c h w -> b c f h w")
+ bs = args.vae_mini_batch
+ new_pixel_values = []
+ for i in range(0, pixel_values.shape[0], bs):
+ pixel_values_bs = pixel_values[i : i + bs]
+ pixel_values_bs = vae.encode(pixel_values_bs)[0]
+ pixel_values_bs = pixel_values_bs.sample()
+ new_pixel_values.append(pixel_values_bs)
+ vae._clear_fake_context_parallel_cache()
+ return torch.cat(new_pixel_values, dim = 0)
+ if vae_stream_1 is not None:
+ vae_stream_1.wait_stream(torch.cuda.current_stream())
+ with torch.cuda.stream(vae_stream_1):
+ latents = _slice_vae(pixel_values)
+ else:
+ latents = _slice_vae(pixel_values)
+ latents = latents * vae.config.scaling_factor
+
+ if args.train_mode != "normal":
+ mask = rearrange(mask, "b f c h w -> b c f h w")
+ mask = 1 - mask
+ mask = resize_mask(mask, latents)
+
+ mask_pixel_values = rearrange(mask_pixel_values, "b f c h w -> b c f h w")
+ bs = args.vae_mini_batch
+ new_mask_pixel_values = []
+ for i in range(0, mask_pixel_values.shape[0], bs):
+ mask_pixel_values_bs = mask_pixel_values[i : i + bs]
+ mask_pixel_values_bs = vae.encode(mask_pixel_values_bs)[0]
+ mask_pixel_values_bs = mask_pixel_values_bs.sample()
+ new_mask_pixel_values.append(mask_pixel_values_bs)
+ vae._clear_fake_context_parallel_cache()
+ mask_latents = torch.cat(new_mask_pixel_values, dim = 0)
+
+ if vae_stream_2 is not None:
+ torch.cuda.current_stream().wait_stream(vae_stream_2)
+
+ inpaint_latents = torch.concat([mask, mask_latents], dim=1)
+ inpaint_latents = t2v_flag[:, None, None, None, None] * inpaint_latents
+ inpaint_latents = inpaint_latents * vae.config.scaling_factor
+ inpaint_latents = rearrange(inpaint_latents, "b c f h w -> b f c h w")
+
+ latents = rearrange(latents, "b c f h w -> b f c h w")
+
+ # wait for latents = vae.encode(pixel_values) to complete
+ if vae_stream_1 is not None:
+ torch.cuda.current_stream().wait_stream(vae_stream_1)
+
+ if args.low_vram:
+ vae.to('cpu')
+ torch.cuda.empty_cache()
+ if not args.enable_text_encoder_in_dataloader:
+ text_encoder.to(accelerator.device)
+
+ if args.enable_text_encoder_in_dataloader:
+ prompt_embeds = batch['encoder_hidden_states'].to(device=latents.device)
+ else:
+ with torch.no_grad():
+ prompt_ids = tokenizer(
+ batch['text'],
+ max_length=args.tokenizer_max_length,
+ padding="max_length",
+ add_special_tokens=True,
+ truncation=True,
+ return_tensors="pt"
+ )
+ prompt_embeds = text_encoder(
+ prompt_ids.input_ids.to(latents.device),
+ return_dict=False
+ )[0]
+
+ if args.low_vram and not args.enable_text_encoder_in_dataloader:
+ text_encoder.to('cpu')
+ torch.cuda.empty_cache()
+
+ bsz = latents.shape[0]
+ noise = torch.randn(latents.size(), device=latents.device, generator=torch_rng, dtype=weight_dtype)
+ # Sample a random timestep for each image
+ # timesteps = generate_timestep_with_lognorm(0, args.train_sampling_steps, (bsz,), device=latents.device, generator=torch_rng)
+ timesteps = torch.randint(0, args.train_sampling_steps, (bsz,), device=latents.device, generator=torch_rng)
+ timesteps = timesteps.long()
+
+ # Similar to diffusers.pipelines.hunyuandit.pipeline_hunyuandit.get_resize_crop_region_for_grid
+ def get_resize_crop_region_for_grid(src, tgt_width, tgt_height):
+ tw = tgt_width
+ th = tgt_height
+ h, w = src
+ r = h / w
+ if r > (th / tw):
+ resize_height = th
+ resize_width = int(round(th / h * w))
+ else:
+ resize_width = tw
+ resize_height = int(round(tw / w * h))
+
+ crop_top = int(round((th - resize_height) / 2.0))
+ crop_left = int(round((tw - resize_width) / 2.0))
+
+ return (crop_top, crop_left), (crop_top + resize_height, crop_left + resize_width)
+
+ def _prepare_rotary_positional_embeddings(
+ height: int,
+ width: int,
+ num_frames: int,
+ device: torch.device
+ ):
+ vae_scale_factor_spatial = (
+ 2 ** (len(vae.config.block_out_channels) - 1) if vae is not None else 8
+ )
+ grid_height = height // (vae_scale_factor_spatial * unwrap_model(transformer3d).config.patch_size)
+ grid_width = width // (vae_scale_factor_spatial * unwrap_model(transformer3d).config.patch_size)
+ base_size_width = 720 // (vae_scale_factor_spatial * unwrap_model(transformer3d).config.patch_size)
+ base_size_height = 480 // (vae_scale_factor_spatial * unwrap_model(transformer3d).config.patch_size)
+
+ grid_crops_coords = get_resize_crop_region_for_grid(
+ (grid_height, grid_width), base_size_width, base_size_height
+ )
+ freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
+ embed_dim=transformer3d.config.attention_head_dim,
+ crops_coords=grid_crops_coords,
+ grid_size=(grid_height, grid_width),
+ temporal_size=num_frames,
+ use_real=True,
+ )
+ freqs_cos = freqs_cos.to(device=device)
+ freqs_sin = freqs_sin.to(device=device)
+ return freqs_cos, freqs_sin
+
+ height, width = batch["pixel_values"].size()[-2], batch["pixel_values"].size()[-1]
+ # 7. Create rotary embeds if required
+ image_rotary_emb = (
+ _prepare_rotary_positional_embeddings(height, width, latents.size(1), latents.device)
+ if unwrap_model(transformer3d).config.use_rotary_positional_embeddings
+ else None
+ )
+ prompt_embeds = prompt_embeds.to(device=latents.device)
+
+ noisy_latents = noise_scheduler.add_noise(latents, noise, timesteps)
+ if noise_scheduler.config.prediction_type == "epsilon":
+ target = noise
+ elif noise_scheduler.config.prediction_type == "v_prediction":
+ target = noise_scheduler.get_velocity(latents, noise, timesteps)
+ else:
+ raise ValueError(f"Unknown prediction type {noise_scheduler.config.prediction_type}")
+
+ # predict the noise residual
+ noise_pred = transformer3d(
+ hidden_states=noisy_latents,
+ encoder_hidden_states=prompt_embeds,
+ timestep=timesteps,
+ image_rotary_emb=image_rotary_emb,
+ return_dict=False,
+ inpaint_latents=inpaint_latents if args.train_mode != "normal" else None,
+ )[0]
+ loss = F.mse_loss(noise_pred.float(), target.float(), reduction="mean")
+
+ if args.motion_sub_loss and noise_pred.size()[1] > 2:
+ gt_sub_noise = noise_pred[:, 1:, :].float() - noise_pred[:, :-1, :].float()
+ pre_sub_noise = target[:, 1:, :].float() - target[:, :-1, :].float()
+ sub_loss = F.mse_loss(gt_sub_noise, pre_sub_noise, reduction="mean")
+ loss = loss * (1 - args.motion_sub_loss_ratio) + sub_loss * args.motion_sub_loss_ratio
+
+ # Gather the losses across all processes for logging (if we use distributed training).
+ avg_loss = accelerator.gather(loss.repeat(args.train_batch_size)).mean()
+ train_loss += avg_loss.item() / args.gradient_accumulation_steps
+
+ # Backpropagate
+ accelerator.backward(loss)
+ if accelerator.sync_gradients:
+ accelerator.clip_grad_norm_(trainable_params, args.max_grad_norm)
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+
+ # Checks if the accelerator has performed an optimization step behind the scenes
+ if accelerator.sync_gradients:
+ progress_bar.update(1)
+ global_step += 1
+ accelerator.log({"train_loss": train_loss}, step=global_step)
+ train_loss = 0.0
+
+ if global_step % args.checkpointing_steps == 0:
+ if args.use_deepspeed or accelerator.is_main_process:
+ # _before_ saving state, check if this save would set us over the `checkpoints_total_limit`
+ if args.checkpoints_total_limit is not None:
+ checkpoints = os.listdir(args.output_dir)
+ checkpoints = [d for d in checkpoints if d.startswith("checkpoint")]
+ checkpoints = sorted(checkpoints, key=lambda x: int(x.split("-")[1]))
+
+ # before we save the new checkpoint, we need to have at _most_ `checkpoints_total_limit - 1` checkpoints
+ if len(checkpoints) >= args.checkpoints_total_limit:
+ num_to_remove = len(checkpoints) - args.checkpoints_total_limit + 1
+ removing_checkpoints = checkpoints[0:num_to_remove]
+
+ logger.info(
+ f"{len(checkpoints)} checkpoints already exist, removing {len(removing_checkpoints)} checkpoints"
+ )
+ logger.info(f"removing checkpoints: {', '.join(removing_checkpoints)}")
+
+ for removing_checkpoint in removing_checkpoints:
+ removing_checkpoint = os.path.join(args.output_dir, removing_checkpoint)
+ shutil.rmtree(removing_checkpoint)
+ if not args.save_state:
+ safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
+ save_model(safetensor_save_path, accelerator.unwrap_model(network))
+ logger.info(f"Saved safetensor to {safetensor_save_path}")
+ else:
+ accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
+ accelerator.save_state(accelerator_save_path)
+ logger.info(f"Saved state to {accelerator_save_path}")
+
+ if accelerator.is_main_process:
+ if args.validation_prompts is not None and global_step % args.validation_steps == 0:
+ log_validation(
+ vae,
+ text_encoder,
+ tokenizer,
+ transformer3d,
+ network,
+ args,
+ accelerator,
+ weight_dtype,
+ global_step,
+ )
+
+ logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
+ progress_bar.set_postfix(**logs)
+
+ if global_step >= args.max_train_steps:
+ break
+
+ if accelerator.is_main_process:
+ if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
+ log_validation(
+ vae,
+ text_encoder,
+ tokenizer,
+ transformer3d,
+ network,
+ args,
+ accelerator,
+ weight_dtype,
+ global_step,
+ )
+
+ # Create the pipeline using the trained modules and save it.
+ accelerator.wait_for_everyone()
+ if accelerator.is_main_process:
+ safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
+ accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
+ save_model(safetensor_save_path, accelerator.unwrap_model(network))
+ if args.save_state:
+ accelerator.save_state(accelerator_save_path)
+ logger.info(f"Saved state to {accelerator_save_path}")
+
+ accelerator.end_training()
+
+
+if __name__ == "__main__":
+ main()
diff --git a/scripts/train_lora.sh b/scripts/train_lora.sh
new file mode 100644
index 0000000..0a8df2f
--- /dev/null
+++ b/scripts/train_lora.sh
@@ -0,0 +1,38 @@
+export MODEL_NAME="models/Diffusion_Transformer/CogVideoX-Fun-2b-InP"
+export DATASET_NAME="datasets/internal_datasets/"
+export DATASET_META_NAME="datasets/internal_datasets/metadata.json"
+export NCCL_IB_DISABLE=1
+export NCCL_P2P_DISABLE=1
+NCCL_DEBUG=INFO
+
+# When train model with multi machines, use "--config_file accelerate.yaml" instead of "--mixed_precision='bf16'".
+accelerate launch --mixed_precision="bf16" scripts/train_lora.py \
+ --pretrained_model_name_or_path=$MODEL_NAME \
+ --train_data_dir=$DATASET_NAME \
+ --train_data_meta=$DATASET_META_NAME \
+ --image_sample_size=1280 \
+ --video_sample_size=256 \
+ --token_sample_size=512 \
+ --video_sample_stride=3 \
+ --video_sample_n_frames=49 \
+ --train_batch_size=1 \
+ --video_repeat=1 \
+ --gradient_accumulation_steps=1 \
+ --dataloader_num_workers=8 \
+ --num_train_epochs=100 \
+ --checkpointing_steps=50 \
+ --learning_rate=1e-04 \
+ --seed=42 \
+ --output_dir="output_dir" \
+ --gradient_checkpointing \
+ --mixed_precision="bf16" \
+ --adam_weight_decay=3e-2 \
+ --adam_epsilon=1e-10 \
+ --vae_mini_batch=1 \
+ --max_grad_norm=0.05 \
+ --random_hw_adapt \
+ --training_with_video_token_length \
+ --random_frame_crop \
+ --enable_bucket \
+ --low_vram \
+ --train_mode="inpaint"
\ No newline at end of file