Initial commit
 kijai
@@ -0,0 +1,9 @@
|
||||
.DS_Store
|
||||
*pyc
|
||||
.vscode
|
||||
__pycache__
|
||||
*.egg-info
|
||||
|
||||
checkpoints
|
||||
results
|
||||
backup
|
||||
@@ -0,0 +1,470 @@
|
||||
This license applies to the source codes that are open sourced in connection with the DynamiCrafter.
|
||||
|
||||
Copyright (C) 2023 THL A29 Limited, a Tencent company.
|
||||
|
||||
Apache License
|
||||
Version 2.0, January 2004
|
||||
http://www.apache.org/licenses/
|
||||
|
||||
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
||||
|
||||
1. Definitions.
|
||||
|
||||
"License" shall mean the terms and conditions for use, reproduction,
|
||||
and distribution as defined by Sections 1 through 9 of this document.
|
||||
|
||||
"Licensor" shall mean the copyright owner or entity authorized by
|
||||
the copyright owner that is granting the License.
|
||||
|
||||
"Legal Entity" shall mean the union of the acting entity and all
|
||||
other entities that control, are controlled by, or are under common
|
||||
control with that entity. For the purposes of this definition,
|
||||
"control" means (i) the power, direct or indirect, to cause the
|
||||
direction or management of such entity, whether by contract or
|
||||
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
||||
outstanding shares, or (iii) beneficial ownership of such entity.
|
||||
|
||||
"You" (or "Your") shall mean an individual or Legal Entity
|
||||
exercising permissions granted by this License.
|
||||
|
||||
"Source" form shall mean the preferred form for making modifications,
|
||||
including but not limited to software source code, documentation
|
||||
source, and configuration files.
|
||||
|
||||
"Object" form shall mean any form resulting from mechanical
|
||||
transformation or translation of a Source form, including but
|
||||
not limited to compiled object code, generated documentation,
|
||||
and conversions to other media types.
|
||||
|
||||
"Work" shall mean the work of authorship, whether in Source or
|
||||
Object form, made available under the License, as indicated by a
|
||||
copyright notice that is included in or attached to the work
|
||||
(an example is provided in the Appendix below).
|
||||
|
||||
"Derivative Works" shall mean any work, whether in Source or Object
|
||||
form, that is based on (or derived from) the Work and for which the
|
||||
editorial revisions, annotations, elaborations, or other modifications
|
||||
represent, as a whole, an original work of authorship. For the purposes
|
||||
of this License, Derivative Works shall not include works that remain
|
||||
separable from, or merely link (or bind by name) to the interfaces of,
|
||||
the Work and Derivative Works thereof.
|
||||
|
||||
"Contribution" shall mean any work of authorship, including
|
||||
the original version of the Work and any modifications or additions
|
||||
to that Work or Derivative Works thereof, that is intentionally
|
||||
submitted to Licensor for inclusion in the Work by the copyright owner
|
||||
or by an individual or Legal Entity authorized to submit on behalf of
|
||||
the copyright owner. For the purposes of this definition, "submitted"
|
||||
means any form of electronic, verbal, or written communication sent
|
||||
to the Licensor or its representatives, including but not limited to
|
||||
communication on electronic mailing lists, source code control systems,
|
||||
and issue tracking systems that are managed by, or on behalf of, the
|
||||
Licensor for the purpose of discussing and improving the Work, but
|
||||
excluding communication that is conspicuously marked or otherwise
|
||||
designated in writing by the copyright owner as "Not a Contribution."
|
||||
|
||||
"Contributor" shall mean Licensor and any individual or Legal Entity
|
||||
on behalf of whom a Contribution has been received by Licensor and
|
||||
subsequently incorporated within the Work.
|
||||
|
||||
2. Grant of Copyright License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
copyright license to reproduce, prepare Derivative Works of,
|
||||
publicly display, publicly perform, sublicense, and distribute the
|
||||
Work and such Derivative Works in Source or Object form.
|
||||
|
||||
3. Grant of Patent License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
(except as stated in this section) patent license to make, have made,
|
||||
use, offer to sell, sell, import, and otherwise transfer the Work,
|
||||
where such license applies only to those patent claims licensable
|
||||
by such Contributor that are necessarily infringed by their
|
||||
Contribution(s) alone or by combination of their Contribution(s)
|
||||
with the Work to which such Contribution(s) was submitted. If You
|
||||
institute patent litigation against any entity (including a
|
||||
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
||||
or a Contribution incorporated within the Work constitutes direct
|
||||
or contributory patent infringement, then any patent licenses
|
||||
granted to You under this License for that Work shall terminate
|
||||
as of the date such litigation is filed.
|
||||
|
||||
4. Redistribution. You may reproduce and distribute copies of the
|
||||
Work or Derivative Works thereof in any medium, with or without
|
||||
modifications, and in Source or Object form, provided that You
|
||||
meet the following conditions:
|
||||
|
||||
(a) You must give any other recipients of the Work or
|
||||
Derivative Works a copy of this License; and
|
||||
|
||||
(b) You must cause any modified files to carry prominent notices
|
||||
stating that You changed the files; and
|
||||
|
||||
(c) You must retain, in the Source form of any Derivative Works
|
||||
that You distribute, all copyright, patent, trademark, and
|
||||
attribution notices from the Source form of the Work,
|
||||
excluding those notices that do not pertain to any part of
|
||||
the Derivative Works; and
|
||||
|
||||
(d) If the Work includes a "NOTICE" text file as part of its
|
||||
distribution, then any Derivative Works that You distribute must
|
||||
include a readable copy of the attribution notices contained
|
||||
within such NOTICE file, excluding those notices that do not
|
||||
pertain to any part of the Derivative Works, in at least one
|
||||
of the following places: within a NOTICE text file distributed
|
||||
as part of the Derivative Works; within the Source form or
|
||||
documentation, if provided along with the Derivative Works; or,
|
||||
within a display generated by the Derivative Works, if and
|
||||
wherever such third-party notices normally appear. The contents
|
||||
of the NOTICE file are for informational purposes only and
|
||||
do not modify the License. You may add Your own attribution
|
||||
notices within Derivative Works that You distribute, alongside
|
||||
or as an addendum to the NOTICE text from the Work, provided
|
||||
that such additional attribution notices cannot be construed
|
||||
as modifying the License.
|
||||
|
||||
You may add Your own copyright statement to Your modifications and
|
||||
may provide additional or different license terms and conditions
|
||||
for use, reproduction, or distribution of Your modifications, or
|
||||
for any such Derivative Works as a whole, provided Your use,
|
||||
reproduction, and distribution of the Work otherwise complies with
|
||||
the conditions stated in this License.
|
||||
|
||||
5. Submission of Contributions. Unless You explicitly state otherwise,
|
||||
any Contribution intentionally submitted for inclusion in the Work
|
||||
by You to the Licensor shall be under the terms and conditions of
|
||||
this License, without any additional terms or conditions.
|
||||
Notwithstanding the above, nothing herein shall supersede or modify
|
||||
the terms of any separate license agreement you may have executed
|
||||
with Licensor regarding such Contributions.
|
||||
|
||||
6. Trademarks. This License does not grant permission to use the trade
|
||||
names, trademarks, service marks, or product names of the Licensor,
|
||||
except as required for reasonable and customary use in describing the
|
||||
origin of the Work and reproducing the content of the NOTICE file.
|
||||
|
||||
7. Disclaimer of Warranty. Unless required by applicable law or
|
||||
agreed to in writing, Licensor provides the Work (and each
|
||||
Contributor provides its Contributions) on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
||||
implied, including, without limitation, any warranties or conditions
|
||||
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
||||
PARTICULAR PURPOSE. You are solely responsible for determining the
|
||||
appropriateness of using or redistributing the Work and assume any
|
||||
risks associated with Your exercise of permissions under this License.
|
||||
|
||||
8. Limitation of Liability. In no event and under no legal theory,
|
||||
whether in tort (including negligence), contract, or otherwise,
|
||||
unless required by applicable law (such as deliberate and grossly
|
||||
negligent acts) or agreed to in writing, shall any Contributor be
|
||||
liable to You for damages, including any direct, indirect, special,
|
||||
incidental, or consequential damages of any character arising as a
|
||||
result of this License or out of the use or inability to use the
|
||||
Work (including but not limited to damages for loss of goodwill,
|
||||
work stoppage, computer failure or malfunction, or any and all
|
||||
other commercial damages or losses), even if such Contributor
|
||||
has been advised of the possibility of such damages.
|
||||
|
||||
9. Accepting Warranty or Additional Liability. While redistributing
|
||||
the Work or Derivative Works thereof, You may choose to offer,
|
||||
and charge a fee for, acceptance of support, warranty, indemnity,
|
||||
or other liability obligations and/or rights consistent with this
|
||||
License. However, in accepting such obligations, You may act only
|
||||
on Your own behalf and on Your sole responsibility, not on behalf
|
||||
of any other Contributor, and only if You agree to indemnify,
|
||||
defend, and hold each Contributor harmless for any liability
|
||||
incurred by, or claims asserted against, such Contributor by reason
|
||||
of your accepting any such warranty or additional liability.
|
||||
|
||||
10. This code is provided for research purposes only and is
|
||||
not to be used for any commercial purposes. By using this code,
|
||||
you agree that it will be used solely for academic research, scholarly work,
|
||||
and non-commercial activities. Any use of this code for commercial purposes,
|
||||
including but not limited to, selling, distributing, or incorporating it into
|
||||
commercial products or services, is strictly prohibited. Violation of this
|
||||
clause may result in legal actions and penalties.
|
||||
|
||||
END OF TERMS AND CONDITIONS
|
||||
|
||||
APPENDIX: How to apply the Apache License to your work.
|
||||
|
||||
To apply the Apache License to your work, attach the following
|
||||
boilerplate notice, with the fields enclosed by brackets "[]"
|
||||
replaced with your own identifying information. (Don't include
|
||||
the brackets!) The text should be enclosed in the appropriate
|
||||
comment syntax for the file format. We also recommend that a
|
||||
file or class name and description of purpose be included on the
|
||||
same "printed page" as the copyright notice for easier
|
||||
identification within third-party archives.
|
||||
|
||||
Copyright [yyyy] [name of copyright owner]
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
|
||||
|
||||
Other dependencies and licenses (if such optional components are used):
|
||||
|
||||
|
||||
Components under BSD 3-Clause License:
|
||||
------------------------------------------------
|
||||
1. numpy
|
||||
Copyright (c) 2005-2022, NumPy Developers.
|
||||
All rights reserved.
|
||||
|
||||
2. pytorch
|
||||
Copyright (c) 2016- Facebook, Inc (Adam Paszke)
|
||||
Copyright (c) 2014- Facebook, Inc (Soumith Chintala)
|
||||
Copyright (c) 2011-2014 Idiap Research Institute (Ronan Collobert)
|
||||
Copyright (c) 2012-2014 Deepmind Technologies (Koray Kavukcuoglu)
|
||||
Copyright (c) 2011-2012 NEC Laboratories America (Koray Kavukcuoglu)
|
||||
Copyright (c) 2011-2013 NYU (Clement Farabet)
|
||||
Copyright (c) 2006-2010 NEC Laboratories America (Ronan Collobert, Leon Bottou, Iain Melvin, Jason Weston)
|
||||
Copyright (c) 2006 Idiap Research Institute (Samy Bengio)
|
||||
Copyright (c) 2001-2004 Idiap Research Institute (Ronan Collobert, Samy Bengio, Johnny Mariethoz)
|
||||
|
||||
3. torchvision
|
||||
Copyright (c) Soumith Chintala 2016,
|
||||
All rights reserved.
|
||||
|
||||
Redistribution and use in source and binary forms, with or without
|
||||
modification, are permitted provided that the following conditions are met:
|
||||
|
||||
* Redistributions of source code must retain the above copyright notice, this
|
||||
list of conditions and the following disclaimer.
|
||||
|
||||
* Redistributions in binary form must reproduce the above copyright notice,
|
||||
this list of conditions and the following disclaimer in the documentation
|
||||
and/or other materials provided with the distribution.
|
||||
|
||||
* Neither the name of the copyright holder nor the names of its
|
||||
contributors may be used to endorse or promote products derived from
|
||||
this software without specific prior written permission.
|
||||
|
||||
THIS SOFTWARE IS PROVIDED BY THE COPYRIGHT HOLDERS AND CONTRIBUTORS "AS IS"
|
||||
AND ANY EXPRESS OR IMPLIED WARRANTIES, INCLUDING, BUT NOT LIMITED TO, THE
|
||||
IMPLIED WARRANTIES OF MERCHANTABILITY AND FITNESS FOR A PARTICULAR PURPOSE ARE
|
||||
DISCLAIMED. IN NO EVENT SHALL THE COPYRIGHT HOLDER OR CONTRIBUTORS BE LIABLE
|
||||
FOR ANY DIRECT, INDIRECT, INCIDENTAL, SPECIAL, EXEMPLARY, OR CONSEQUENTIAL
|
||||
DAMAGES (INCLUDING, BUT NOT LIMITED TO, PROCUREMENT OF SUBSTITUTE GOODS OR
|
||||
SERVICES; LOSS OF USE, DATA, OR PROFITS; OR BUSINESS INTERRUPTION) HOWEVER
|
||||
CAUSED AND ON ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, STRICT LIABILITY,
|
||||
OR TORT (INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE
|
||||
OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
|
||||
|
||||
Component under Apache v2 License:
|
||||
-----------------------------------------------------
|
||||
1. timm
|
||||
Copyright 2019 Ross Wightman
|
||||
|
||||
Apache License
|
||||
Version 2.0, January 2004
|
||||
http://www.apache.org/licenses/
|
||||
|
||||
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
||||
|
||||
1. Definitions.
|
||||
|
||||
"License" shall mean the terms and conditions for use, reproduction,
|
||||
and distribution as defined by Sections 1 through 9 of this document.
|
||||
|
||||
"Licensor" shall mean the copyright owner or entity authorized by
|
||||
the copyright owner that is granting the License.
|
||||
|
||||
"Legal Entity" shall mean the union of the acting entity and all
|
||||
other entities that control, are controlled by, or are under common
|
||||
control with that entity. For the purposes of this definition,
|
||||
"control" means (i) the power, direct or indirect, to cause the
|
||||
direction or management of such entity, whether by contract or
|
||||
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
||||
outstanding shares, or (iii) beneficial ownership of such entity.
|
||||
|
||||
"You" (or "Your") shall mean an individual or Legal Entity
|
||||
exercising permissions granted by this License.
|
||||
|
||||
"Source" form shall mean the preferred form for making modifications,
|
||||
including but not limited to software source code, documentation
|
||||
source, and configuration files.
|
||||
|
||||
"Object" form shall mean any form resulting from mechanical
|
||||
transformation or translation of a Source form, including but
|
||||
not limited to compiled object code, generated documentation,
|
||||
and conversions to other media types.
|
||||
|
||||
"Work" shall mean the work of authorship, whether in Source or
|
||||
Object form, made available under the License, as indicated by a
|
||||
copyright notice that is included in or attached to the work
|
||||
(an example is provided in the Appendix below).
|
||||
|
||||
"Derivative Works" shall mean any work, whether in Source or Object
|
||||
form, that is based on (or derived from) the Work and for which the
|
||||
editorial revisions, annotations, elaborations, or other modifications
|
||||
represent, as a whole, an original work of authorship. For the purposes
|
||||
of this License, Derivative Works shall not include works that remain
|
||||
separable from, or merely link (or bind by name) to the interfaces of,
|
||||
the Work and Derivative Works thereof.
|
||||
|
||||
"Contribution" shall mean any work of authorship, including
|
||||
the original version of the Work and any modifications or additions
|
||||
to that Work or Derivative Works thereof, that is intentionally
|
||||
submitted to Licensor for inclusion in the Work by the copyright owner
|
||||
or by an individual or Legal Entity authorized to submit on behalf of
|
||||
the copyright owner. For the purposes of this definition, "submitted"
|
||||
means any form of electronic, verbal, or written communication sent
|
||||
to the Licensor or its representatives, including but not limited to
|
||||
communication on electronic mailing lists, source code control systems,
|
||||
and issue tracking systems that are managed by, or on behalf of, the
|
||||
Licensor for the purpose of discussing and improving the Work, but
|
||||
excluding communication that is conspicuously marked or otherwise
|
||||
designated in writing by the copyright owner as "Not a Contribution."
|
||||
|
||||
"Contributor" shall mean Licensor and any individual or Legal Entity
|
||||
on behalf of whom a Contribution has been received by Licensor and
|
||||
subsequently incorporated within the Work.
|
||||
|
||||
2. Grant of Copyright License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
copyright license to reproduce, prepare Derivative Works of,
|
||||
publicly display, publicly perform, sublicense, and distribute the
|
||||
Work and such Derivative Works in Source or Object form.
|
||||
|
||||
3. Grant of Patent License. Subject to the terms and conditions of
|
||||
this License, each Contributor hereby grants to You a perpetual,
|
||||
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
||||
(except as stated in this section) patent license to make, have made,
|
||||
use, offer to sell, sell, import, and otherwise transfer the Work,
|
||||
where such license applies only to those patent claims licensable
|
||||
by such Contributor that are necessarily infringed by their
|
||||
Contribution(s) alone or by combination of their Contribution(s)
|
||||
with the Work to which such Contribution(s) was submitted. If You
|
||||
institute patent litigation against any entity (including a
|
||||
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
||||
or a Contribution incorporated within the Work constitutes direct
|
||||
or contributory patent infringement, then any patent licenses
|
||||
granted to You under this License for that Work shall terminate
|
||||
as of the date such litigation is filed.
|
||||
|
||||
4. Redistribution. You may reproduce and distribute copies of the
|
||||
Work or Derivative Works thereof in any medium, with or without
|
||||
modifications, and in Source or Object form, provided that You
|
||||
meet the following conditions:
|
||||
|
||||
(a) You must give any other recipients of the Work or
|
||||
Derivative Works a copy of this License; and
|
||||
|
||||
(b) You must cause any modified files to carry prominent notices
|
||||
stating that You changed the files; and
|
||||
|
||||
(c) You must retain, in the Source form of any Derivative Works
|
||||
that You distribute, all copyright, patent, trademark, and
|
||||
attribution notices from the Source form of the Work,
|
||||
excluding those notices that do not pertain to any part of
|
||||
the Derivative Works; and
|
||||
|
||||
(d) If the Work includes a "NOTICE" text file as part of its
|
||||
distribution, then any Derivative Works that You distribute must
|
||||
include a readable copy of the attribution notices contained
|
||||
within such NOTICE file, excluding those notices that do not
|
||||
pertain to any part of the Derivative Works, in at least one
|
||||
of the following places: within a NOTICE text file distributed
|
||||
as part of the Derivative Works; within the Source form or
|
||||
documentation, if provided along with the Derivative Works; or,
|
||||
within a display generated by the Derivative Works, if and
|
||||
wherever such third-party notices normally appear. The contents
|
||||
of the NOTICE file are for informational purposes only and
|
||||
do not modify the License. You may add Your own attribution
|
||||
notices within Derivative Works that You distribute, alongside
|
||||
or as an addendum to the NOTICE text from the Work, provided
|
||||
that such additional attribution notices cannot be construed
|
||||
as modifying the License.
|
||||
|
||||
You may add Your own copyright statement to Your modifications and
|
||||
may provide additional or different license terms and conditions
|
||||
for use, reproduction, or distribution of Your modifications, or
|
||||
for any such Derivative Works as a whole, provided Your use,
|
||||
reproduction, and distribution of the Work otherwise complies with
|
||||
the conditions stated in this License.
|
||||
|
||||
5. Submission of Contributions. Unless You explicitly state otherwise,
|
||||
any Contribution intentionally submitted for inclusion in the Work
|
||||
by You to the Licensor shall be under the terms and conditions of
|
||||
this License, without any additional terms or conditions.
|
||||
Notwithstanding the above, nothing herein shall supersede or modify
|
||||
the terms of any separate license agreement you may have executed
|
||||
with Licensor regarding such Contributions.
|
||||
|
||||
6. Trademarks. This License does not grant permission to use the trade
|
||||
names, trademarks, service marks, or product names of the Licensor,
|
||||
except as required for reasonable and customary use in describing the
|
||||
origin of the Work and reproducing the content of the NOTICE file.
|
||||
|
||||
7. Disclaimer of Warranty. Unless required by applicable law or
|
||||
agreed to in writing, Licensor provides the Work (and each
|
||||
Contributor provides its Contributions) on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
||||
implied, including, without limitation, any warranties or conditions
|
||||
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
||||
PARTICULAR PURPOSE. You are solely responsible for determining the
|
||||
appropriateness of using or redistributing the Work and assume any
|
||||
risks associated with Your exercise of permissions under this License.
|
||||
|
||||
8. Limitation of Liability. In no event and under no legal theory,
|
||||
whether in tort (including negligence), contract, or otherwise,
|
||||
unless required by applicable law (such as deliberate and grossly
|
||||
negligent acts) or agreed to in writing, shall any Contributor be
|
||||
liable to You for damages, including any direct, indirect, special,
|
||||
incidental, or consequential damages of any character arising as a
|
||||
result of this License or out of the use or inability to use the
|
||||
Work (including but not limited to damages for loss of goodwill,
|
||||
work stoppage, computer failure or malfunction, or any and all
|
||||
other commercial damages or losses), even if such Contributor
|
||||
has been advised of the possibility of such damages.
|
||||
|
||||
9. Accepting Warranty or Additional Liability. While redistributing
|
||||
the Work or Derivative Works thereof, You may choose to offer,
|
||||
and charge a fee for, acceptance of support, warranty, indemnity,
|
||||
or other liability obligations and/or rights consistent with this
|
||||
License. However, in accepting such obligations, You may act only
|
||||
on Your own behalf and on Your sole responsibility, not on behalf
|
||||
of any other Contributor, and only if You agree to indemnify,
|
||||
defend, and hold each Contributor harmless for any liability
|
||||
incurred by, or claims asserted against, such Contributor by reason
|
||||
of your accepting any such warranty or additional liability.
|
||||
|
||||
END OF TERMS AND CONDITIONS
|
||||
|
||||
APPENDIX: How to apply the Apache License to your work.
|
||||
|
||||
To apply the Apache License to your work, attach the following
|
||||
boilerplate notice, with the fields enclosed by brackets "[]"
|
||||
replaced with your own identifying information. (Don't include
|
||||
the brackets!) The text should be enclosed in the appropriate
|
||||
comment syntax for the file format. We also recommend that a
|
||||
file or class name and description of purpose be included on the
|
||||
same "printed page" as the copyright notice for easier
|
||||
identification within third-party archives.
|
||||
|
||||
Copyright [yyyy] [name of copyright owner]
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
@@ -0,0 +1,373 @@
|
||||
## ___***DynamiCrafter: Animating Open-domain Images with Video Diffusion Priors***___
|
||||
<!-- {: width="50%"} -->
|
||||
<!--  -->
|
||||
<div align="center">
|
||||
<img src='assets/logo_long.png' style="height:100px"></img>
|
||||
|
||||
|
||||
|
||||
|
||||
<a href='https://arxiv.org/abs/2310.12190'><img src='https://img.shields.io/badge/arXiv-2310.12190-b31b1b.svg'></a>
|
||||
<a href='https://doubiiu.github.io/projects/DynamiCrafter/'><img src='https://img.shields.io/badge/Project-Page-Green'></a>
|
||||
<a href='https://huggingface.co/spaces/Doubiiu/DynamiCrafter'><img src='https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Demo-blue'></a>
|
||||
<a href='https://youtu.be/0NfmIsNAg-g'><img src='https://img.shields.io/badge/Youtube-Video-b31b1b.svg'></a><br>
|
||||
[](https://openxlab.org.cn/apps/detail/JinboXING/DynamiCrafter)
|
||||
<a href='https://replicate.com/camenduru/dynami-crafter-576x1024'><img src='https://img.shields.io/badge/replicate-Demo-blue'></a>
|
||||
<a href='https://github.com/camenduru/DynamiCrafter-colab'><img src='https://img.shields.io/badge/Colab-Demo-Green'></a> <a href='https://huggingface.co/papers/2310.12190'><img src='https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Page-blue'></a>
|
||||
|
||||
_**[Jinbo Xing](https://doubiiu.github.io/), [Menghan Xia*](https://menghanxia.github.io), [Yong Zhang](https://yzhang2016.github.io), [Haoxin Chen](), [Wangbo Yu](), <br>[Hanyuan Liu](https://github.com/hyliu), [Xintao Wang](https://xinntao.github.io/), [Tien-Tsin Wong*](https://www.cse.cuhk.edu.hk/~ttwong/myself.html), [Ying Shan](https://scholar.google.com/citations?hl=en&user=4oXBp9UAAAAJ&view_op=list_works&sortby=pubdate)**_
|
||||
<br><br>
|
||||
(* corresponding authors)
|
||||
|
||||
From CUHK and Tencent AI Lab.
|
||||
|
||||
</div>
|
||||
|
||||
## 🔆 Introduction
|
||||
🔥🔥 Generative frame interpolation / looping video generation model weights (320x512) have been released!
|
||||
|
||||
🔥 New Update Rolls Out for DynamiCrafter! Better Dynamic, Higher Resolution, and Stronger Coherence! <br>
|
||||
🤗 DynamiCrafter can animate open-domain still images based on <strong>text prompt</strong> by leveraging the pre-trained video diffusion priors. Please check our project page and paper for more information. <br>
|
||||
😀 We will continue to improve the model's performance.
|
||||
|
||||
👀 Seeking comparisons with [Stable Video Diffusion](https://stability.ai/news/stable-video-diffusion-open-ai-video-model) and [PikaLabs](https://pika.art/)? Click the image below.
|
||||
[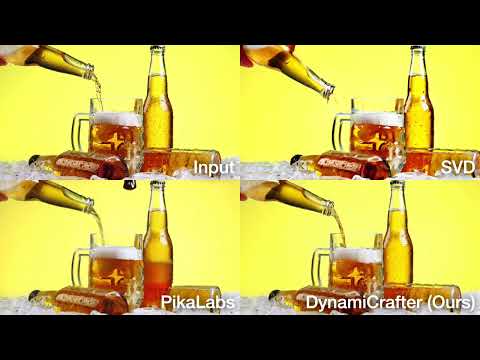](https://www.youtube.com/watch?v=0NfmIsNAg-g)
|
||||
|
||||
|
||||
### 1.1. Showcases (576x1024)
|
||||
<table class="center">
|
||||
<!-- <tr>
|
||||
<td colspan="1">"fireworks display"</td>
|
||||
<td colspan="1">"a robot is walking through a destroyed city"</td>
|
||||
</tr> -->
|
||||
<tr>
|
||||
<td>
|
||||
<img src=assets/showcase/firework03.gif width="340">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/showcase/robot01.gif width="340">
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<!-- <tr>
|
||||
<td colspan="1">"riding a bike under a bridge"</td>
|
||||
<td colspan="1">""</td>
|
||||
</tr> -->
|
||||
<tr>
|
||||
<td>
|
||||
<img src=assets/showcase/bike_chineseink.gif width="340">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/showcase/girl07.gif width="340">
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
### 1.2. Showcases (320x512)
|
||||
<table class="center">
|
||||
<!-- <tr>
|
||||
<td colspan="1">"fireworks display"</td>
|
||||
<td colspan="1">"a robot is walking through a destroyed city"</td>
|
||||
</tr> -->
|
||||
<tr>
|
||||
<td>
|
||||
<img src=assets/showcase/bloom2.gif width="340">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/showcase/train_anime02.gif width="340">
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<!-- <tr>
|
||||
<td colspan="1">"riding a bike under a bridge"</td>
|
||||
<td colspan="1">""</td>
|
||||
</tr> -->
|
||||
<tr>
|
||||
<td>
|
||||
<img src=assets/showcase/pour_honey.gif width="340">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/showcase/lighthouse.gif width="340">
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
|
||||
|
||||
### 1.3. Showcases (256x256)
|
||||
|
||||
<table class="center">
|
||||
<tr>
|
||||
<td colspan="2">"bear playing guitar happily, snowing"</td>
|
||||
<td colspan="2">"boy walking on the street"</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<img src=assets/showcase/guitar0.jpeg_00.png width="170">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/showcase/guitar0.gif width="170">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/showcase/walk0.png_00.png width="170">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/showcase/walk0.gif width="170">
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
|
||||
<!-- <tr>
|
||||
<td colspan="2">"two people dancing"</td>
|
||||
<td colspan="2">"girl talking and blinking"</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<img src=assets/showcase/dance1.jpeg_00.png width="170">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/showcase/dance1.gif width="170">
|
||||
</td>
|
||||
|
||||
<td>
|
||||
<img src=assets/showcase/girl3.jpeg_00.png width="170">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/showcase/girl3.gif width="170">
|
||||
</td>
|
||||
</tr> -->
|
||||
|
||||
|
||||
<!-- <tr>
|
||||
<td colspan="2">"zoom-in, a landscape, springtime"</td>
|
||||
<td colspan="2">"A blonde woman rides on top of a moving <br>washing machine into the sunset."</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<img src=assets/showcase/Upscaled_Aime_Tribolet_springtime_landscape_golden_hour_morning_pale_yel_e6946f8d-37c1-4ce8-bf62-6ba90d23bd93.mp4_00.png width="170">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/showcase/Upscaled_Aime_Tribolet_springtime_landscape_golden_hour_morning_pale_yel_e6946f8d-37c1-4ce8-bf62-6ba90d23bd93.gif width="170">
|
||||
</td>
|
||||
|
||||
<td>
|
||||
<img src=assets/showcase/Upscaled_Alex__State_Blonde_woman_riding_on_top_of_a_moving_washing_mach_c31acaa3-dd30-459f-a109-2d2eb4c00fe2.mp4_00.png width="170">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/showcase/Upscaled_Alex__State_Blonde_woman_riding_on_top_of_a_moving_washing_mach_c31acaa3-dd30-459f-a109-2d2eb4c00fe2.gif width="170">
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
<tr>
|
||||
<td colspan="2">"explode colorful smoke coming out"</td>
|
||||
<td colspan="2">"a bird on the tree branch"</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<img src=assets/showcase/explode0.jpeg_00.png width="170">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/showcase/explode0.gif width="170">
|
||||
</td>
|
||||
|
||||
<td>
|
||||
<img src=assets/showcase/bird000.jpeg width="170">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/showcase/bird000.gif width="170">
|
||||
</td>
|
||||
</tr> -->
|
||||
</table >
|
||||
|
||||
### 2. Applications
|
||||
#### 2.1 Storytelling video generation (see project page for more details)
|
||||
<table class="center">
|
||||
<!-- <tr style="font-weight: bolder;text-align:center;">
|
||||
<td>Input</td>
|
||||
<td>Output</td>
|
||||
<td>Input</td>
|
||||
<td>Output</td>
|
||||
</tr> -->
|
||||
<tr>
|
||||
<td colspan="4"><img src=assets/application/storytellingvideo.gif width="250"></td>
|
||||
</tr>
|
||||
</table >
|
||||
|
||||
#### 2.2 Generative frame interpolation
|
||||
|
||||
<table class="center">
|
||||
<tr style="font-weight: bolder;text-align:center;">
|
||||
<td>Input starting frame</td>
|
||||
<td>Input ending frame</td>
|
||||
<td>Generated video</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<img src=assets/application/gkxX0kb8mE8_input_start.png width="250">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/application/gkxX0kb8mE8_input_end.png width="250">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/application/gkxX0kb8mE8.gif width="250">
|
||||
</td>
|
||||
</tr>
|
||||
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
<img src=assets/application/smile_start.png width="250">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/application/smile_end.png width="250">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/application/smile.gif width="250">
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<img src=assets/application/stone01_start.png width="250">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/application/stone01_end.png width="250">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/application/stone01.gif width="250">
|
||||
</td>
|
||||
</tr>
|
||||
</table >
|
||||
|
||||
#### 2.3 Looping video generation
|
||||
<table class="center">
|
||||
|
||||
<tr>
|
||||
<td>
|
||||
<img src=assets/application/60.gif width="300">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/application/35.gif width="300">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/application/36.gif width="300">
|
||||
</td>
|
||||
</tr>
|
||||
<!-- <tr>
|
||||
<td>
|
||||
<img src=assets/application/05.gif width="300">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/application/25.gif width="300">
|
||||
</td>
|
||||
<td>
|
||||
<img src=assets/application/34.gif width="300">
|
||||
</td>
|
||||
</tr> -->
|
||||
</table >
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## 📝 Changelog
|
||||
- __[2024.03.14]__: 🔥🔥 Release generative frame interpolation and looping video models (320x512).
|
||||
- __[2024.02.05]__: Release high-resolution models (320x512 & 576x1024).
|
||||
- __[2023.12.02]__: Launch the local Gradio demo.
|
||||
- __[2023.11.29]__: Release the main model at a resolution of 256x256.
|
||||
- __[2023.11.27]__: Launch the project page and update the arXiv preprint.
|
||||
<br>
|
||||
|
||||
|
||||
## 🧰 Models
|
||||
|
||||
|Model|Resolution|GPU Mem. & Inference Time (A100, ddim 50steps)|Checkpoint|
|
||||
|:---------|:---------|:--------|:--------|
|
||||
|DynamiCrafter1024|576x1024|18.3GB & 75s (`perframe_ae=True`)|[Hugging Face](https://huggingface.co/Doubiiu/DynamiCrafter_1024/blob/main/model.ckpt)|
|
||||
|DynamiCrafter512|320x512|12.8GB & 20s (`perframe_ae=True`)|[Hugging Face](https://huggingface.co/Doubiiu/DynamiCrafter_512/blob/main/model.ckpt)|
|
||||
|DynamiCrafter256|256x256|11.9GB & 10s (`perframe_ae=False`)|[Hugging Face](https://huggingface.co/Doubiiu/DynamiCrafter/blob/main/model.ckpt)|
|
||||
|DynamiCrafter512_interp|320x512|12.8GB & 20s (`perframe_ae=True`)|[Hugging Face](https://huggingface.co/Doubiiu/DynamiCrafter_512_Interp/blob/main/model.ckpt)|
|
||||
|
||||
|
||||
Currently, our DynamiCrafter can support generating videos of up to 16 frames with a resolution of 576x1024. The inference time can be reduced by using fewer DDIM steps.
|
||||
|
||||
GPU memory consumed on RTX 4090 reported by @noguchis in [Twitter](https://x.com/noguchis/status/1754488826016432341?s=20): 18.3GB (576x1024), 12.8GB (320x512), 11.9GB (256x256).
|
||||
<!-- It takes approximately 10 seconds and requires a peak GPU memory of 20 GB to animate an image using a single NVIDIA A100 (40G) GPU. -->
|
||||
|
||||
## ⚙️ Setup
|
||||
|
||||
### Install Environment via Anaconda (Recommended)
|
||||
```bash
|
||||
conda create -n dynamicrafter python=3.8.5
|
||||
conda activate dynamicrafter
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
|
||||
## 💫 Inference
|
||||
### 1. Command line
|
||||
### Image-to-Video Generation
|
||||
1) Download pretrained models via Hugging Face, and put the `model.ckpt` with the required resolution in `checkpoints/dynamicrafter_[1024|512|256]_v1/model.ckpt`.
|
||||
2) Run the commands based on your devices and needs in terminal.
|
||||
```bash
|
||||
# Run on a single GPU:
|
||||
# Select the model based on required resolutions: i.e., 1024|512|320:
|
||||
sh scripts/run.sh 1024
|
||||
# Run on multiple GPUs for parallel inference:
|
||||
sh scripts/run_mp.sh 1024
|
||||
```
|
||||
|
||||
### Generative Frame Interpolation / Looping Video Generation
|
||||
Download pretrained model DynamiCrafter512_interp and put the `model.ckpt` in `checkpoints/dynamicrafter_512_interp_v1/model.ckpt`.
|
||||
```bash
|
||||
sh scripts/run_application.sh interp # Generate frame interpolation
|
||||
sh scripts/run_application.sh loop # Looping video generation
|
||||
```
|
||||
|
||||
|
||||
### 2. Local Gradio demo
|
||||
### Image-to-Video Generation
|
||||
1. Download the pretrained models and put them in the corresponding directory according to the previous guidelines.
|
||||
2. Input the following commands in terminal (choose a model based on the required resolution: 1024, 512 or 256).
|
||||
```bash
|
||||
python gradio_app.py --res 1024
|
||||
```
|
||||
|
||||
### Generative Frame Interpolation / Looping Video Generation
|
||||
Download the pretrained model and put it in the corresponding directory according to the previous guidelines.
|
||||
```bash
|
||||
python gradio_app_interp_and_loop.py
|
||||
```
|
||||
|
||||
Community Extensions for Image-to-Video: [ComfyUI](https://github.com/chaojie/ComfyUI-DynamiCrafter) (Thanks to [chaojie](https://github.com/chaojie)).
|
||||
|
||||
|
||||
## 👨👩👧👦 Crafter Family
|
||||
[VideoCrafter1](https://github.com/AILab-CVC/VideoCrafter): Framework for high-quality video generation.
|
||||
|
||||
[ScaleCrafter](https://github.com/YingqingHe/ScaleCrafter): Tuning-free method for high-resolution image/video generation.
|
||||
|
||||
[TaleCrafter](https://github.com/AILab-CVC/TaleCrafter): An interactive story visualization tool that supports multiple characters.
|
||||
|
||||
[LongerCrafter](https://github.com/arthur-qiu/LongerCrafter): Tuning-free method for longer high-quality video generation.
|
||||
|
||||
[MakeYourVideo, might be a Crafter:)](https://doubiiu.github.io/projects/Make-Your-Video/): Video generation/editing with textual and structural guidance.
|
||||
|
||||
[StyleCrafter](https://gongyeliu.github.io/StyleCrafter.github.io/): Stylized-image-guided text-to-image and text-to-video generation.
|
||||
## 😉 Citation
|
||||
```bib
|
||||
@article{xing2023dynamicrafter,
|
||||
title={DynamiCrafter: Animating Open-domain Images with Video Diffusion Priors},
|
||||
author={Xing, Jinbo and Xia, Menghan and Zhang, Yong and Chen, Haoxin and Yu, Wangbo and Liu, Hanyuan and Wang, Xintao and Wong, Tien-Tsin and Shan, Ying},
|
||||
journal={arXiv preprint arXiv:2310.12190},
|
||||
year={2023}
|
||||
}
|
||||
```
|
||||
|
||||
## 🙏 Acknowledgements
|
||||
We would like to thank [AK(@_akhaliq)](https://twitter.com/_akhaliq?lang=en) for the help of setting up hugging face online demo, and [camenduru](https://twitter.com/camenduru) for providing the replicate & colab online demo.
|
||||
|
||||
## 📢 Disclaimer
|
||||
We develop this repository for RESEARCH purposes, so it can only be used for personal/research/non-commercial purposes.
|
||||
****
|
||||
@@ -0,0 +1,3 @@
|
||||
from .nodes import NODE_CLASS_MAPPINGS, NODE_DISPLAY_NAME_MAPPINGS
|
||||
|
||||
__all__ = ["NODE_CLASS_MAPPINGS", "NODE_DISPLAY_NAME_MAPPINGS"]
|
||||
@@ -0,0 +1,103 @@
|
||||
model:
|
||||
target: .lvdm.models.ddpm3d.LatentVisualDiffusion
|
||||
params:
|
||||
rescale_betas_zero_snr: True
|
||||
parameterization: "v"
|
||||
linear_start: 0.00085
|
||||
linear_end: 0.012
|
||||
num_timesteps_cond: 1
|
||||
timesteps: 1000
|
||||
first_stage_key: video
|
||||
cond_stage_key: caption
|
||||
cond_stage_trainable: False
|
||||
conditioning_key: hybrid
|
||||
image_size: [72, 128]
|
||||
channels: 4
|
||||
scale_by_std: False
|
||||
scale_factor: 0.18215
|
||||
use_ema: False
|
||||
uncond_type: 'empty_seq'
|
||||
use_dynamic_rescale: true
|
||||
base_scale: 0.3
|
||||
fps_condition_type: 'fps'
|
||||
perframe_ae: True
|
||||
unet_config:
|
||||
target: .lvdm.modules.networks.openaimodel3d.UNetModel
|
||||
params:
|
||||
in_channels: 8
|
||||
out_channels: 4
|
||||
model_channels: 320
|
||||
attention_resolutions:
|
||||
- 4
|
||||
- 2
|
||||
- 1
|
||||
num_res_blocks: 2
|
||||
channel_mult:
|
||||
- 1
|
||||
- 2
|
||||
- 4
|
||||
- 4
|
||||
dropout: 0.1
|
||||
num_head_channels: 64
|
||||
transformer_depth: 1
|
||||
context_dim: 1024
|
||||
use_linear: true
|
||||
use_checkpoint: True
|
||||
temporal_conv: True
|
||||
temporal_attention: True
|
||||
temporal_selfatt_only: true
|
||||
use_relative_position: false
|
||||
use_causal_attention: False
|
||||
temporal_length: 16
|
||||
addition_attention: true
|
||||
image_cross_attention: true
|
||||
default_fs: 10
|
||||
fs_condition: true
|
||||
|
||||
first_stage_config:
|
||||
target: .lvdm.models.autoencoder.AutoencoderKL
|
||||
params:
|
||||
embed_dim: 4
|
||||
monitor: val/rec_loss
|
||||
ddconfig:
|
||||
double_z: True
|
||||
z_channels: 4
|
||||
resolution: 256
|
||||
in_channels: 3
|
||||
out_ch: 3
|
||||
ch: 128
|
||||
ch_mult:
|
||||
- 1
|
||||
- 2
|
||||
- 4
|
||||
- 4
|
||||
num_res_blocks: 2
|
||||
attn_resolutions: []
|
||||
dropout: 0.0
|
||||
lossconfig:
|
||||
target: torch.nn.Identity
|
||||
|
||||
cond_stage_config:
|
||||
target: .lvdm.modules.encoders.condition.FrozenOpenCLIPEmbedder
|
||||
params:
|
||||
freeze: true
|
||||
layer: "penultimate"
|
||||
|
||||
img_cond_stage_config:
|
||||
target: .lvdm.modules.encoders.condition.FrozenOpenCLIPImageEmbedderV2
|
||||
params:
|
||||
freeze: true
|
||||
|
||||
image_proj_stage_config:
|
||||
target: .lvdm.modules.encoders.resampler.Resampler
|
||||
params:
|
||||
dim: 1024
|
||||
depth: 4
|
||||
dim_head: 64
|
||||
heads: 12
|
||||
num_queries: 16
|
||||
embedding_dim: 1280
|
||||
output_dim: 1024
|
||||
ff_mult: 4
|
||||
video_length: 16
|
||||
|
||||
@@ -0,0 +1,98 @@
|
||||
model:
|
||||
target: lvdm.models.ddpm3d.LatentVisualDiffusion
|
||||
params:
|
||||
linear_start: 0.00085
|
||||
linear_end: 0.012
|
||||
num_timesteps_cond: 1
|
||||
timesteps: 1000
|
||||
first_stage_key: video
|
||||
cond_stage_key: caption
|
||||
cond_stage_trainable: False
|
||||
conditioning_key: hybrid
|
||||
image_size: [32, 32]
|
||||
channels: 4
|
||||
scale_by_std: False
|
||||
scale_factor: 0.18215
|
||||
use_ema: False
|
||||
uncond_type: 'empty_seq'
|
||||
unet_config:
|
||||
target: lvdm.modules.networks.openaimodel3d.UNetModel
|
||||
params:
|
||||
in_channels: 8
|
||||
out_channels: 4
|
||||
model_channels: 320
|
||||
attention_resolutions:
|
||||
- 4
|
||||
- 2
|
||||
- 1
|
||||
num_res_blocks: 2
|
||||
channel_mult:
|
||||
- 1
|
||||
- 2
|
||||
- 4
|
||||
- 4
|
||||
dropout: 0.1
|
||||
num_head_channels: 64
|
||||
transformer_depth: 1
|
||||
context_dim: 1024
|
||||
use_linear: true
|
||||
use_checkpoint: True
|
||||
temporal_conv: True
|
||||
temporal_attention: True
|
||||
temporal_selfatt_only: true
|
||||
use_relative_position: false
|
||||
use_causal_attention: False
|
||||
temporal_length: 16
|
||||
addition_attention: true
|
||||
image_cross_attention: true
|
||||
image_cross_attention_scale_learnable: true
|
||||
default_fs: 3
|
||||
fs_condition: true
|
||||
|
||||
first_stage_config:
|
||||
target: lvdm.models.autoencoder.AutoencoderKL
|
||||
params:
|
||||
embed_dim: 4
|
||||
monitor: val/rec_loss
|
||||
ddconfig:
|
||||
double_z: True
|
||||
z_channels: 4
|
||||
resolution: 256
|
||||
in_channels: 3
|
||||
out_ch: 3
|
||||
ch: 128
|
||||
ch_mult:
|
||||
- 1
|
||||
- 2
|
||||
- 4
|
||||
- 4
|
||||
num_res_blocks: 2
|
||||
attn_resolutions: []
|
||||
dropout: 0.0
|
||||
lossconfig:
|
||||
target: torch.nn.Identity
|
||||
|
||||
cond_stage_config:
|
||||
target: lvdm.modules.encoders.condition.FrozenOpenCLIPEmbedder
|
||||
params:
|
||||
freeze: true
|
||||
layer: "penultimate"
|
||||
|
||||
img_cond_stage_config:
|
||||
target: lvdm.modules.encoders.condition.FrozenOpenCLIPImageEmbedderV2
|
||||
params:
|
||||
freeze: true
|
||||
|
||||
image_proj_stage_config:
|
||||
target: lvdm.modules.encoders.resampler.Resampler
|
||||
params:
|
||||
dim: 1024
|
||||
depth: 4
|
||||
dim_head: 64
|
||||
heads: 12
|
||||
num_queries: 16
|
||||
embedding_dim: 1280
|
||||
output_dim: 1024
|
||||
ff_mult: 4
|
||||
video_length: 16
|
||||
|
||||
@@ -0,0 +1,103 @@
|
||||
model:
|
||||
target: lvdm.models.ddpm3d.LatentVisualDiffusion
|
||||
params:
|
||||
rescale_betas_zero_snr: True
|
||||
parameterization: "v"
|
||||
linear_start: 0.00085
|
||||
linear_end: 0.012
|
||||
num_timesteps_cond: 1
|
||||
timesteps: 1000
|
||||
first_stage_key: video
|
||||
cond_stage_key: caption
|
||||
cond_stage_trainable: False
|
||||
conditioning_key: hybrid
|
||||
image_size: [40, 64]
|
||||
channels: 4
|
||||
scale_by_std: False
|
||||
scale_factor: 0.18215
|
||||
use_ema: False
|
||||
uncond_type: 'empty_seq'
|
||||
use_dynamic_rescale: true
|
||||
base_scale: 0.7
|
||||
fps_condition_type: 'fps'
|
||||
perframe_ae: True
|
||||
unet_config:
|
||||
target: lvdm.modules.networks.openaimodel3d.UNetModel
|
||||
params:
|
||||
in_channels: 8
|
||||
out_channels: 4
|
||||
model_channels: 320
|
||||
attention_resolutions:
|
||||
- 4
|
||||
- 2
|
||||
- 1
|
||||
num_res_blocks: 2
|
||||
channel_mult:
|
||||
- 1
|
||||
- 2
|
||||
- 4
|
||||
- 4
|
||||
dropout: 0.1
|
||||
num_head_channels: 64
|
||||
transformer_depth: 1
|
||||
context_dim: 1024
|
||||
use_linear: true
|
||||
use_checkpoint: True
|
||||
temporal_conv: True
|
||||
temporal_attention: True
|
||||
temporal_selfatt_only: true
|
||||
use_relative_position: false
|
||||
use_causal_attention: False
|
||||
temporal_length: 16
|
||||
addition_attention: true
|
||||
image_cross_attention: true
|
||||
default_fs: 24
|
||||
fs_condition: true
|
||||
|
||||
first_stage_config:
|
||||
target: lvdm.models.autoencoder.AutoencoderKL
|
||||
params:
|
||||
embed_dim: 4
|
||||
monitor: val/rec_loss
|
||||
ddconfig:
|
||||
double_z: True
|
||||
z_channels: 4
|
||||
resolution: 256
|
||||
in_channels: 3
|
||||
out_ch: 3
|
||||
ch: 128
|
||||
ch_mult:
|
||||
- 1
|
||||
- 2
|
||||
- 4
|
||||
- 4
|
||||
num_res_blocks: 2
|
||||
attn_resolutions: []
|
||||
dropout: 0.0
|
||||
lossconfig:
|
||||
target: torch.nn.Identity
|
||||
|
||||
cond_stage_config:
|
||||
target: lvdm.modules.encoders.condition.FrozenOpenCLIPEmbedder
|
||||
params:
|
||||
freeze: true
|
||||
layer: "penultimate"
|
||||
|
||||
img_cond_stage_config:
|
||||
target: lvdm.modules.encoders.condition.FrozenOpenCLIPImageEmbedderV2
|
||||
params:
|
||||
freeze: true
|
||||
|
||||
image_proj_stage_config:
|
||||
target: lvdm.modules.encoders.resampler.Resampler
|
||||
params:
|
||||
dim: 1024
|
||||
depth: 4
|
||||
dim_head: 64
|
||||
heads: 12
|
||||
num_queries: 16
|
||||
embedding_dim: 1280
|
||||
output_dim: 1024
|
||||
ff_mult: 4
|
||||
video_length: 16
|
||||
|
||||
@@ -0,0 +1,100 @@
|
||||
# adopted from
|
||||
# https://github.com/openai/improved-diffusion/blob/main/improved_diffusion/gaussian_diffusion.py
|
||||
# and
|
||||
# https://github.com/lucidrains/denoising-diffusion-pytorch/blob/7706bdfc6f527f58d33f84b7b522e61e6e3164b3/denoising_diffusion_pytorch/denoising_diffusion_pytorch.py
|
||||
# and
|
||||
# https://github.com/openai/guided-diffusion/blob/0ba878e517b276c45d1195eb29f6f5f72659a05b/guided_diffusion/nn.py
|
||||
#
|
||||
# thanks!
|
||||
|
||||
import torch.nn as nn
|
||||
from ..utils.utils import instantiate_from_config
|
||||
|
||||
|
||||
def disabled_train(self, mode=True):
|
||||
"""Overwrite model.train with this function to make sure train/eval mode
|
||||
does not change anymore."""
|
||||
return self
|
||||
|
||||
def zero_module(module):
|
||||
"""
|
||||
Zero out the parameters of a module and return it.
|
||||
"""
|
||||
for p in module.parameters():
|
||||
p.detach().zero_()
|
||||
return module
|
||||
|
||||
def scale_module(module, scale):
|
||||
"""
|
||||
Scale the parameters of a module and return it.
|
||||
"""
|
||||
for p in module.parameters():
|
||||
p.detach().mul_(scale)
|
||||
return module
|
||||
|
||||
|
||||
def conv_nd(dims, *args, **kwargs):
|
||||
"""
|
||||
Create a 1D, 2D, or 3D convolution module.
|
||||
"""
|
||||
if dims == 1:
|
||||
return nn.Conv1d(*args, **kwargs)
|
||||
elif dims == 2:
|
||||
return nn.Conv2d(*args, **kwargs)
|
||||
elif dims == 3:
|
||||
return nn.Conv3d(*args, **kwargs)
|
||||
raise ValueError(f"unsupported dimensions: {dims}")
|
||||
|
||||
|
||||
def linear(*args, **kwargs):
|
||||
"""
|
||||
Create a linear module.
|
||||
"""
|
||||
return nn.Linear(*args, **kwargs)
|
||||
|
||||
|
||||
def avg_pool_nd(dims, *args, **kwargs):
|
||||
"""
|
||||
Create a 1D, 2D, or 3D average pooling module.
|
||||
"""
|
||||
if dims == 1:
|
||||
return nn.AvgPool1d(*args, **kwargs)
|
||||
elif dims == 2:
|
||||
return nn.AvgPool2d(*args, **kwargs)
|
||||
elif dims == 3:
|
||||
return nn.AvgPool3d(*args, **kwargs)
|
||||
raise ValueError(f"unsupported dimensions: {dims}")
|
||||
|
||||
|
||||
def nonlinearity(type='silu'):
|
||||
if type == 'silu':
|
||||
return nn.SiLU()
|
||||
elif type == 'leaky_relu':
|
||||
return nn.LeakyReLU()
|
||||
|
||||
|
||||
class GroupNormSpecific(nn.GroupNorm):
|
||||
def forward(self, x):
|
||||
return super().forward(x.float()).type(x.dtype)
|
||||
|
||||
|
||||
def normalization(channels, num_groups=32):
|
||||
"""
|
||||
Make a standard normalization layer.
|
||||
:param channels: number of input channels.
|
||||
:return: an nn.Module for normalization.
|
||||
"""
|
||||
return GroupNormSpecific(num_groups, channels)
|
||||
|
||||
|
||||
class HybridConditioner(nn.Module):
|
||||
|
||||
def __init__(self, c_concat_config, c_crossattn_config):
|
||||
super().__init__()
|
||||
self.concat_conditioner = instantiate_from_config(c_concat_config)
|
||||
self.crossattn_conditioner = instantiate_from_config(c_crossattn_config)
|
||||
|
||||
def forward(self, c_concat, c_crossattn):
|
||||
c_concat = self.concat_conditioner(c_concat)
|
||||
c_crossattn = self.crossattn_conditioner(c_crossattn)
|
||||
return {'c_concat': [c_concat], 'c_crossattn': [c_crossattn]}
|
||||
@@ -0,0 +1,94 @@
|
||||
import math
|
||||
from inspect import isfunction
|
||||
import torch
|
||||
from torch import nn
|
||||
import torch.distributed as dist
|
||||
|
||||
|
||||
def gather_data(data, return_np=True):
|
||||
''' gather data from multiple processes to one list '''
|
||||
data_list = [torch.zeros_like(data) for _ in range(dist.get_world_size())]
|
||||
dist.all_gather(data_list, data) # gather not supported with NCCL
|
||||
if return_np:
|
||||
data_list = [data.cpu().numpy() for data in data_list]
|
||||
return data_list
|
||||
|
||||
def autocast(f):
|
||||
def do_autocast(*args, **kwargs):
|
||||
with torch.cuda.amp.autocast(enabled=True,
|
||||
dtype=torch.get_autocast_gpu_dtype(),
|
||||
cache_enabled=torch.is_autocast_cache_enabled()):
|
||||
return f(*args, **kwargs)
|
||||
return do_autocast
|
||||
|
||||
|
||||
def extract_into_tensor(a, t, x_shape):
|
||||
b, *_ = t.shape
|
||||
out = a.gather(-1, t)
|
||||
return out.reshape(b, *((1,) * (len(x_shape) - 1)))
|
||||
|
||||
|
||||
def noise_like(shape, device, repeat=False):
|
||||
repeat_noise = lambda: torch.randn((1, *shape[1:]), device=device).repeat(shape[0], *((1,) * (len(shape) - 1)))
|
||||
noise = lambda: torch.randn(shape, device=device)
|
||||
return repeat_noise() if repeat else noise()
|
||||
|
||||
|
||||
def default(val, d):
|
||||
if exists(val):
|
||||
return val
|
||||
return d() if isfunction(d) else d
|
||||
|
||||
def exists(val):
|
||||
return val is not None
|
||||
|
||||
def identity(*args, **kwargs):
|
||||
return nn.Identity()
|
||||
|
||||
def uniq(arr):
|
||||
return{el: True for el in arr}.keys()
|
||||
|
||||
def mean_flat(tensor):
|
||||
"""
|
||||
Take the mean over all non-batch dimensions.
|
||||
"""
|
||||
return tensor.mean(dim=list(range(1, len(tensor.shape))))
|
||||
|
||||
def ismap(x):
|
||||
if not isinstance(x, torch.Tensor):
|
||||
return False
|
||||
return (len(x.shape) == 4) and (x.shape[1] > 3)
|
||||
|
||||
def isimage(x):
|
||||
if not isinstance(x,torch.Tensor):
|
||||
return False
|
||||
return (len(x.shape) == 4) and (x.shape[1] == 3 or x.shape[1] == 1)
|
||||
|
||||
def max_neg_value(t):
|
||||
return -torch.finfo(t.dtype).max
|
||||
|
||||
def shape_to_str(x):
|
||||
shape_str = "x".join([str(x) for x in x.shape])
|
||||
return shape_str
|
||||
|
||||
def init_(tensor):
|
||||
dim = tensor.shape[-1]
|
||||
std = 1 / math.sqrt(dim)
|
||||
tensor.uniform_(-std, std)
|
||||
return tensor
|
||||
|
||||
ckpt = torch.utils.checkpoint.checkpoint
|
||||
def checkpoint(func, inputs, params, flag):
|
||||
"""
|
||||
Evaluate a function without caching intermediate activations, allowing for
|
||||
reduced memory at the expense of extra compute in the backward pass.
|
||||
:param func: the function to evaluate.
|
||||
:param inputs: the argument sequence to pass to `func`.
|
||||
:param params: a sequence of parameters `func` depends on but does not
|
||||
explicitly take as arguments.
|
||||
:param flag: if False, disable gradient checkpointing.
|
||||
"""
|
||||
if flag:
|
||||
return ckpt(func, *inputs, use_reentrant=False)
|
||||
else:
|
||||
return func(*inputs)
|
||||
@@ -0,0 +1,95 @@
|
||||
import torch
|
||||
import numpy as np
|
||||
|
||||
|
||||
class AbstractDistribution:
|
||||
def sample(self):
|
||||
raise NotImplementedError()
|
||||
|
||||
def mode(self):
|
||||
raise NotImplementedError()
|
||||
|
||||
|
||||
class DiracDistribution(AbstractDistribution):
|
||||
def __init__(self, value):
|
||||
self.value = value
|
||||
|
||||
def sample(self):
|
||||
return self.value
|
||||
|
||||
def mode(self):
|
||||
return self.value
|
||||
|
||||
|
||||
class DiagonalGaussianDistribution(object):
|
||||
def __init__(self, parameters, deterministic=False):
|
||||
self.parameters = parameters
|
||||
self.mean, self.logvar = torch.chunk(parameters, 2, dim=1)
|
||||
self.logvar = torch.clamp(self.logvar, -30.0, 20.0)
|
||||
self.deterministic = deterministic
|
||||
self.std = torch.exp(0.5 * self.logvar)
|
||||
self.var = torch.exp(self.logvar)
|
||||
if self.deterministic:
|
||||
self.var = self.std = torch.zeros_like(self.mean).to(device=self.parameters.device)
|
||||
|
||||
def sample(self, noise=None):
|
||||
if noise is None:
|
||||
noise = torch.randn(self.mean.shape)
|
||||
|
||||
x = self.mean + self.std * noise.to(device=self.parameters.device)
|
||||
return x
|
||||
|
||||
def kl(self, other=None):
|
||||
if self.deterministic:
|
||||
return torch.Tensor([0.])
|
||||
else:
|
||||
if other is None:
|
||||
return 0.5 * torch.sum(torch.pow(self.mean, 2)
|
||||
+ self.var - 1.0 - self.logvar,
|
||||
dim=[1, 2, 3])
|
||||
else:
|
||||
return 0.5 * torch.sum(
|
||||
torch.pow(self.mean - other.mean, 2) / other.var
|
||||
+ self.var / other.var - 1.0 - self.logvar + other.logvar,
|
||||
dim=[1, 2, 3])
|
||||
|
||||
def nll(self, sample, dims=[1,2,3]):
|
||||
if self.deterministic:
|
||||
return torch.Tensor([0.])
|
||||
logtwopi = np.log(2.0 * np.pi)
|
||||
return 0.5 * torch.sum(
|
||||
logtwopi + self.logvar + torch.pow(sample - self.mean, 2) / self.var,
|
||||
dim=dims)
|
||||
|
||||
def mode(self):
|
||||
return self.mean
|
||||
|
||||
|
||||
def normal_kl(mean1, logvar1, mean2, logvar2):
|
||||
"""
|
||||
source: https://github.com/openai/guided-diffusion/blob/27c20a8fab9cb472df5d6bdd6c8d11c8f430b924/guided_diffusion/losses.py#L12
|
||||
Compute the KL divergence between two gaussians.
|
||||
Shapes are automatically broadcasted, so batches can be compared to
|
||||
scalars, among other use cases.
|
||||
"""
|
||||
tensor = None
|
||||
for obj in (mean1, logvar1, mean2, logvar2):
|
||||
if isinstance(obj, torch.Tensor):
|
||||
tensor = obj
|
||||
break
|
||||
assert tensor is not None, "at least one argument must be a Tensor"
|
||||
|
||||
# Force variances to be Tensors. Broadcasting helps convert scalars to
|
||||
# Tensors, but it does not work for torch.exp().
|
||||
logvar1, logvar2 = [
|
||||
x if isinstance(x, torch.Tensor) else torch.tensor(x).to(tensor)
|
||||
for x in (logvar1, logvar2)
|
||||
]
|
||||
|
||||
return 0.5 * (
|
||||
-1.0
|
||||
+ logvar2
|
||||
- logvar1
|
||||
+ torch.exp(logvar1 - logvar2)
|
||||
+ ((mean1 - mean2) ** 2) * torch.exp(-logvar2)
|
||||
)
|
||||
@@ -0,0 +1,76 @@
|
||||
import torch
|
||||
from torch import nn
|
||||
|
||||
|
||||
class LitEma(nn.Module):
|
||||
def __init__(self, model, decay=0.9999, use_num_upates=True):
|
||||
super().__init__()
|
||||
if decay < 0.0 or decay > 1.0:
|
||||
raise ValueError('Decay must be between 0 and 1')
|
||||
|
||||
self.m_name2s_name = {}
|
||||
self.register_buffer('decay', torch.tensor(decay, dtype=torch.float32))
|
||||
self.register_buffer('num_updates', torch.tensor(0,dtype=torch.int) if use_num_upates
|
||||
else torch.tensor(-1,dtype=torch.int))
|
||||
|
||||
for name, p in model.named_parameters():
|
||||
if p.requires_grad:
|
||||
#remove as '.'-character is not allowed in buffers
|
||||
s_name = name.replace('.','')
|
||||
self.m_name2s_name.update({name:s_name})
|
||||
self.register_buffer(s_name,p.clone().detach().data)
|
||||
|
||||
self.collected_params = []
|
||||
|
||||
def forward(self,model):
|
||||
decay = self.decay
|
||||
|
||||
if self.num_updates >= 0:
|
||||
self.num_updates += 1
|
||||
decay = min(self.decay,(1 + self.num_updates) / (10 + self.num_updates))
|
||||
|
||||
one_minus_decay = 1.0 - decay
|
||||
|
||||
with torch.no_grad():
|
||||
m_param = dict(model.named_parameters())
|
||||
shadow_params = dict(self.named_buffers())
|
||||
|
||||
for key in m_param:
|
||||
if m_param[key].requires_grad:
|
||||
sname = self.m_name2s_name[key]
|
||||
shadow_params[sname] = shadow_params[sname].type_as(m_param[key])
|
||||
shadow_params[sname].sub_(one_minus_decay * (shadow_params[sname] - m_param[key]))
|
||||
else:
|
||||
assert not key in self.m_name2s_name
|
||||
|
||||
def copy_to(self, model):
|
||||
m_param = dict(model.named_parameters())
|
||||
shadow_params = dict(self.named_buffers())
|
||||
for key in m_param:
|
||||
if m_param[key].requires_grad:
|
||||
m_param[key].data.copy_(shadow_params[self.m_name2s_name[key]].data)
|
||||
else:
|
||||
assert not key in self.m_name2s_name
|
||||
|
||||
def store(self, parameters):
|
||||
"""
|
||||
Save the current parameters for restoring later.
|
||||
Args:
|
||||
parameters: Iterable of `torch.nn.Parameter`; the parameters to be
|
||||
temporarily stored.
|
||||
"""
|
||||
self.collected_params = [param.clone() for param in parameters]
|
||||
|
||||
def restore(self, parameters):
|
||||
"""
|
||||
Restore the parameters stored with the `store` method.
|
||||
Useful to validate the model with EMA parameters without affecting the
|
||||
original optimization process. Store the parameters before the
|
||||
`copy_to` method. After validation (or model saving), use this to
|
||||
restore the former parameters.
|
||||
Args:
|
||||
parameters: Iterable of `torch.nn.Parameter`; the parameters to be
|
||||
updated with the stored parameters.
|
||||
"""
|
||||
for c_param, param in zip(self.collected_params, parameters):
|
||||
param.data.copy_(c_param.data)
|
||||
@@ -0,0 +1,219 @@
|
||||
import os
|
||||
from contextlib import contextmanager
|
||||
import torch
|
||||
import numpy as np
|
||||
from einops import rearrange
|
||||
import torch.nn.functional as F
|
||||
import pytorch_lightning as pl
|
||||
from ...lvdm.modules.networks.ae_modules import Encoder, Decoder
|
||||
from ...lvdm.distributions import DiagonalGaussianDistribution
|
||||
from ...utils.utils import instantiate_from_config
|
||||
|
||||
|
||||
class AutoencoderKL(pl.LightningModule):
|
||||
def __init__(self,
|
||||
ddconfig,
|
||||
lossconfig,
|
||||
embed_dim,
|
||||
ckpt_path=None,
|
||||
ignore_keys=[],
|
||||
image_key="image",
|
||||
colorize_nlabels=None,
|
||||
monitor=None,
|
||||
test=False,
|
||||
logdir=None,
|
||||
input_dim=4,
|
||||
test_args=None,
|
||||
):
|
||||
super().__init__()
|
||||
self.image_key = image_key
|
||||
self.encoder = Encoder(**ddconfig)
|
||||
self.decoder = Decoder(**ddconfig)
|
||||
self.loss = instantiate_from_config(lossconfig)
|
||||
assert ddconfig["double_z"]
|
||||
self.quant_conv = torch.nn.Conv2d(2*ddconfig["z_channels"], 2*embed_dim, 1)
|
||||
self.post_quant_conv = torch.nn.Conv2d(embed_dim, ddconfig["z_channels"], 1)
|
||||
self.embed_dim = embed_dim
|
||||
self.input_dim = input_dim
|
||||
self.test = test
|
||||
self.test_args = test_args
|
||||
self.logdir = logdir
|
||||
if colorize_nlabels is not None:
|
||||
assert type(colorize_nlabels)==int
|
||||
self.register_buffer("colorize", torch.randn(3, colorize_nlabels, 1, 1))
|
||||
if monitor is not None:
|
||||
self.monitor = monitor
|
||||
if ckpt_path is not None:
|
||||
self.init_from_ckpt(ckpt_path, ignore_keys=ignore_keys)
|
||||
if self.test:
|
||||
self.init_test()
|
||||
|
||||
def init_test(self,):
|
||||
self.test = True
|
||||
save_dir = os.path.join(self.logdir, "test")
|
||||
if 'ckpt' in self.test_args:
|
||||
ckpt_name = os.path.basename(self.test_args.ckpt).split('.ckpt')[0] + f'_epoch{self._cur_epoch}'
|
||||
self.root = os.path.join(save_dir, ckpt_name)
|
||||
else:
|
||||
self.root = save_dir
|
||||
if 'test_subdir' in self.test_args:
|
||||
self.root = os.path.join(save_dir, self.test_args.test_subdir)
|
||||
|
||||
self.root_zs = os.path.join(self.root, "zs")
|
||||
self.root_dec = os.path.join(self.root, "reconstructions")
|
||||
self.root_inputs = os.path.join(self.root, "inputs")
|
||||
os.makedirs(self.root, exist_ok=True)
|
||||
|
||||
if self.test_args.save_z:
|
||||
os.makedirs(self.root_zs, exist_ok=True)
|
||||
if self.test_args.save_reconstruction:
|
||||
os.makedirs(self.root_dec, exist_ok=True)
|
||||
if self.test_args.save_input:
|
||||
os.makedirs(self.root_inputs, exist_ok=True)
|
||||
assert(self.test_args is not None)
|
||||
self.test_maximum = getattr(self.test_args, 'test_maximum', None)
|
||||
self.count = 0
|
||||
self.eval_metrics = {}
|
||||
self.decodes = []
|
||||
self.save_decode_samples = 2048
|
||||
|
||||
def init_from_ckpt(self, path, ignore_keys=list()):
|
||||
sd = torch.load(path, map_location="cpu")
|
||||
try:
|
||||
self._cur_epoch = sd['epoch']
|
||||
sd = sd["state_dict"]
|
||||
except:
|
||||
self._cur_epoch = 'null'
|
||||
keys = list(sd.keys())
|
||||
for k in keys:
|
||||
for ik in ignore_keys:
|
||||
if k.startswith(ik):
|
||||
print("Deleting key {} from state_dict.".format(k))
|
||||
del sd[k]
|
||||
self.load_state_dict(sd, strict=False)
|
||||
# self.load_state_dict(sd, strict=True)
|
||||
print(f"Restored from {path}")
|
||||
|
||||
def encode(self, x, **kwargs):
|
||||
|
||||
h = self.encoder(x)
|
||||
moments = self.quant_conv(h)
|
||||
posterior = DiagonalGaussianDistribution(moments)
|
||||
return posterior
|
||||
|
||||
def decode(self, z, **kwargs):
|
||||
z = self.post_quant_conv(z)
|
||||
dec = self.decoder(z)
|
||||
return dec
|
||||
|
||||
def forward(self, input, sample_posterior=True):
|
||||
posterior = self.encode(input)
|
||||
if sample_posterior:
|
||||
z = posterior.sample()
|
||||
else:
|
||||
z = posterior.mode()
|
||||
dec = self.decode(z)
|
||||
return dec, posterior
|
||||
|
||||
def get_input(self, batch, k):
|
||||
x = batch[k]
|
||||
if x.dim() == 5 and self.input_dim == 4:
|
||||
b,c,t,h,w = x.shape
|
||||
self.b = b
|
||||
self.t = t
|
||||
x = rearrange(x, 'b c t h w -> (b t) c h w')
|
||||
|
||||
return x
|
||||
|
||||
def training_step(self, batch, batch_idx, optimizer_idx):
|
||||
inputs = self.get_input(batch, self.image_key)
|
||||
reconstructions, posterior = self(inputs)
|
||||
|
||||
if optimizer_idx == 0:
|
||||
# train encoder+decoder+logvar
|
||||
aeloss, log_dict_ae = self.loss(inputs, reconstructions, posterior, optimizer_idx, self.global_step,
|
||||
last_layer=self.get_last_layer(), split="train")
|
||||
self.log("aeloss", aeloss, prog_bar=True, logger=True, on_step=True, on_epoch=True)
|
||||
self.log_dict(log_dict_ae, prog_bar=False, logger=True, on_step=True, on_epoch=False)
|
||||
return aeloss
|
||||
|
||||
if optimizer_idx == 1:
|
||||
# train the discriminator
|
||||
discloss, log_dict_disc = self.loss(inputs, reconstructions, posterior, optimizer_idx, self.global_step,
|
||||
last_layer=self.get_last_layer(), split="train")
|
||||
|
||||
self.log("discloss", discloss, prog_bar=True, logger=True, on_step=True, on_epoch=True)
|
||||
self.log_dict(log_dict_disc, prog_bar=False, logger=True, on_step=True, on_epoch=False)
|
||||
return discloss
|
||||
|
||||
def validation_step(self, batch, batch_idx):
|
||||
inputs = self.get_input(batch, self.image_key)
|
||||
reconstructions, posterior = self(inputs)
|
||||
aeloss, log_dict_ae = self.loss(inputs, reconstructions, posterior, 0, self.global_step,
|
||||
last_layer=self.get_last_layer(), split="val")
|
||||
|
||||
discloss, log_dict_disc = self.loss(inputs, reconstructions, posterior, 1, self.global_step,
|
||||
last_layer=self.get_last_layer(), split="val")
|
||||
|
||||
self.log("val/rec_loss", log_dict_ae["val/rec_loss"])
|
||||
self.log_dict(log_dict_ae)
|
||||
self.log_dict(log_dict_disc)
|
||||
return self.log_dict
|
||||
|
||||
def configure_optimizers(self):
|
||||
lr = self.learning_rate
|
||||
opt_ae = torch.optim.Adam(list(self.encoder.parameters())+
|
||||
list(self.decoder.parameters())+
|
||||
list(self.quant_conv.parameters())+
|
||||
list(self.post_quant_conv.parameters()),
|
||||
lr=lr, betas=(0.5, 0.9))
|
||||
opt_disc = torch.optim.Adam(self.loss.discriminator.parameters(),
|
||||
lr=lr, betas=(0.5, 0.9))
|
||||
return [opt_ae, opt_disc], []
|
||||
|
||||
def get_last_layer(self):
|
||||
return self.decoder.conv_out.weight
|
||||
|
||||
@torch.no_grad()
|
||||
def log_images(self, batch, only_inputs=False, **kwargs):
|
||||
log = dict()
|
||||
x = self.get_input(batch, self.image_key)
|
||||
x = x.to(self.device)
|
||||
if not only_inputs:
|
||||
xrec, posterior = self(x)
|
||||
if x.shape[1] > 3:
|
||||
# colorize with random projection
|
||||
assert xrec.shape[1] > 3
|
||||
x = self.to_rgb(x)
|
||||
xrec = self.to_rgb(xrec)
|
||||
log["samples"] = self.decode(torch.randn_like(posterior.sample()))
|
||||
log["reconstructions"] = xrec
|
||||
log["inputs"] = x
|
||||
return log
|
||||
|
||||
def to_rgb(self, x):
|
||||
assert self.image_key == "segmentation"
|
||||
if not hasattr(self, "colorize"):
|
||||
self.register_buffer("colorize", torch.randn(3, x.shape[1], 1, 1).to(x))
|
||||
x = F.conv2d(x, weight=self.colorize)
|
||||
x = 2.*(x-x.min())/(x.max()-x.min()) - 1.
|
||||
return x
|
||||
|
||||
class IdentityFirstStage(torch.nn.Module):
|
||||
def __init__(self, *args, vq_interface=False, **kwargs):
|
||||
self.vq_interface = vq_interface # TODO: Should be true by default but check to not break older stuff
|
||||
super().__init__()
|
||||
|
||||
def encode(self, x, *args, **kwargs):
|
||||
return x
|
||||
|
||||
def decode(self, x, *args, **kwargs):
|
||||
return x
|
||||
|
||||
def quantize(self, x, *args, **kwargs):
|
||||
if self.vq_interface:
|
||||
return x, None, [None, None, None]
|
||||
return x
|
||||
|
||||
def forward(self, x, *args, **kwargs):
|
||||
return x
|
||||
@@ -0,0 +1,762 @@
|
||||
"""
|
||||
wild mixture of
|
||||
https://github.com/openai/improved-diffusion/blob/e94489283bb876ac1477d5dd7709bbbd2d9902ce/improved_diffusion/gaussian_diffusion.py
|
||||
https://github.com/lucidrains/denoising-diffusion-pytorch/blob/7706bdfc6f527f58d33f84b7b522e61e6e3164b3/denoising_diffusion_pytorch/denoising_diffusion_pytorch.py
|
||||
https://github.com/CompVis/taming-transformers
|
||||
-- merci
|
||||
"""
|
||||
|
||||
from functools import partial
|
||||
from contextlib import contextmanager
|
||||
import numpy as np
|
||||
from tqdm import tqdm
|
||||
from einops import rearrange, repeat
|
||||
import logging
|
||||
mainlogger = logging.getLogger('mainlogger')
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from torchvision.utils import make_grid
|
||||
import pytorch_lightning as pl
|
||||
from ...utils.utils import instantiate_from_config
|
||||
from ...lvdm.ema import LitEma
|
||||
from ...lvdm.distributions import DiagonalGaussianDistribution
|
||||
from ...lvdm.models.utils_diffusion import make_beta_schedule, rescale_zero_terminal_snr
|
||||
from ...lvdm.basics import disabled_train
|
||||
from ...lvdm.common import (
|
||||
extract_into_tensor,
|
||||
noise_like,
|
||||
exists,
|
||||
default
|
||||
)
|
||||
|
||||
__conditioning_keys__ = {'concat': 'c_concat',
|
||||
'crossattn': 'c_crossattn',
|
||||
'adm': 'y'}
|
||||
|
||||
class DDPM(pl.LightningModule):
|
||||
# classic DDPM with Gaussian diffusion, in image space
|
||||
def __init__(self,
|
||||
unet_config,
|
||||
timesteps=1000,
|
||||
beta_schedule="linear",
|
||||
loss_type="l2",
|
||||
ckpt_path=None,
|
||||
ignore_keys=[],
|
||||
load_only_unet=False,
|
||||
monitor=None,
|
||||
use_ema=True,
|
||||
first_stage_key="image",
|
||||
image_size=256,
|
||||
channels=3,
|
||||
log_every_t=100,
|
||||
clip_denoised=True,
|
||||
linear_start=1e-4,
|
||||
linear_end=2e-2,
|
||||
cosine_s=8e-3,
|
||||
given_betas=None,
|
||||
original_elbo_weight=0.,
|
||||
v_posterior=0., # weight for choosing posterior variance as sigma = (1-v) * beta_tilde + v * beta
|
||||
l_simple_weight=1.,
|
||||
conditioning_key=None,
|
||||
parameterization="eps", # all assuming fixed variance schedules
|
||||
scheduler_config=None,
|
||||
use_positional_encodings=False,
|
||||
learn_logvar=False,
|
||||
logvar_init=0.,
|
||||
rescale_betas_zero_snr=False,
|
||||
):
|
||||
super().__init__()
|
||||
assert parameterization in ["eps", "x0", "v"], 'currently only supporting "eps" and "x0" and "v"'
|
||||
self.parameterization = parameterization
|
||||
mainlogger.info(f"{self.__class__.__name__}: Running in {self.parameterization}-prediction mode")
|
||||
self.cond_stage_model = None
|
||||
self.clip_denoised = clip_denoised
|
||||
self.log_every_t = log_every_t
|
||||
self.first_stage_key = first_stage_key
|
||||
self.channels = channels
|
||||
self.temporal_length = unet_config.params.temporal_length
|
||||
self.image_size = image_size # try conv?
|
||||
if isinstance(self.image_size, int):
|
||||
self.image_size = [self.image_size, self.image_size]
|
||||
self.use_positional_encodings = use_positional_encodings
|
||||
self.model = DiffusionWrapper(unet_config, conditioning_key)
|
||||
#count_params(self.model, verbose=True)
|
||||
self.use_ema = use_ema
|
||||
self.rescale_betas_zero_snr = rescale_betas_zero_snr
|
||||
if self.use_ema:
|
||||
self.model_ema = LitEma(self.model)
|
||||
mainlogger.info(f"Keeping EMAs of {len(list(self.model_ema.buffers()))}.")
|
||||
|
||||
self.use_scheduler = scheduler_config is not None
|
||||
if self.use_scheduler:
|
||||
self.scheduler_config = scheduler_config
|
||||
|
||||
self.v_posterior = v_posterior
|
||||
self.original_elbo_weight = original_elbo_weight
|
||||
self.l_simple_weight = l_simple_weight
|
||||
|
||||
if monitor is not None:
|
||||
self.monitor = monitor
|
||||
if ckpt_path is not None:
|
||||
self.init_from_ckpt(ckpt_path, ignore_keys=ignore_keys, only_model=load_only_unet)
|
||||
|
||||
self.register_schedule(given_betas=given_betas, beta_schedule=beta_schedule, timesteps=timesteps,
|
||||
linear_start=linear_start, linear_end=linear_end, cosine_s=cosine_s)
|
||||
|
||||
self.loss_type = loss_type
|
||||
|
||||
self.learn_logvar = learn_logvar
|
||||
self.logvar = torch.full(fill_value=logvar_init, size=(self.num_timesteps,))
|
||||
if self.learn_logvar:
|
||||
self.logvar = nn.Parameter(self.logvar, requires_grad=True)
|
||||
|
||||
def register_schedule(self, given_betas=None, beta_schedule="linear", timesteps=1000,
|
||||
linear_start=1e-4, linear_end=2e-2, cosine_s=8e-3):
|
||||
if exists(given_betas):
|
||||
betas = given_betas
|
||||
else:
|
||||
betas = make_beta_schedule(beta_schedule, timesteps, linear_start=linear_start, linear_end=linear_end,
|
||||
cosine_s=cosine_s)
|
||||
if self.rescale_betas_zero_snr:
|
||||
betas = rescale_zero_terminal_snr(betas)
|
||||
|
||||
alphas = 1. - betas
|
||||
alphas_cumprod = np.cumprod(alphas, axis=0)
|
||||
alphas_cumprod_prev = np.append(1., alphas_cumprod[:-1])
|
||||
|
||||
timesteps, = betas.shape
|
||||
self.num_timesteps = int(timesteps)
|
||||
self.linear_start = linear_start
|
||||
self.linear_end = linear_end
|
||||
assert alphas_cumprod.shape[0] == self.num_timesteps, 'alphas have to be defined for each timestep'
|
||||
|
||||
to_torch = partial(torch.tensor, dtype=torch.float32)
|
||||
|
||||
self.register_buffer('betas', to_torch(betas))
|
||||
self.register_buffer('alphas_cumprod', to_torch(alphas_cumprod))
|
||||
self.register_buffer('alphas_cumprod_prev', to_torch(alphas_cumprod_prev))
|
||||
|
||||
# calculations for diffusion q(x_t | x_{t-1}) and others
|
||||
self.register_buffer('sqrt_alphas_cumprod', to_torch(np.sqrt(alphas_cumprod)))
|
||||
self.register_buffer('sqrt_one_minus_alphas_cumprod', to_torch(np.sqrt(1. - alphas_cumprod)))
|
||||
self.register_buffer('log_one_minus_alphas_cumprod', to_torch(np.log(1. - alphas_cumprod)))
|
||||
|
||||
if self.parameterization != 'v':
|
||||
self.register_buffer('sqrt_recip_alphas_cumprod', to_torch(np.sqrt(1. / alphas_cumprod)))
|
||||
self.register_buffer('sqrt_recipm1_alphas_cumprod', to_torch(np.sqrt(1. / alphas_cumprod - 1)))
|
||||
else:
|
||||
self.register_buffer('sqrt_recip_alphas_cumprod', torch.zeros_like(to_torch(alphas_cumprod)))
|
||||
self.register_buffer('sqrt_recipm1_alphas_cumprod', torch.zeros_like(to_torch(alphas_cumprod)))
|
||||
|
||||
# calculations for posterior q(x_{t-1} | x_t, x_0)
|
||||
posterior_variance = (1 - self.v_posterior) * betas * (1. - alphas_cumprod_prev) / (
|
||||
1. - alphas_cumprod) + self.v_posterior * betas
|
||||
# above: equal to 1. / (1. / (1. - alpha_cumprod_tm1) + alpha_t / beta_t)
|
||||
self.register_buffer('posterior_variance', to_torch(posterior_variance))
|
||||
# below: log calculation clipped because the posterior variance is 0 at the beginning of the diffusion chain
|
||||
self.register_buffer('posterior_log_variance_clipped', to_torch(np.log(np.maximum(posterior_variance, 1e-20))))
|
||||
self.register_buffer('posterior_mean_coef1', to_torch(
|
||||
betas * np.sqrt(alphas_cumprod_prev) / (1. - alphas_cumprod)))
|
||||
self.register_buffer('posterior_mean_coef2', to_torch(
|
||||
(1. - alphas_cumprod_prev) * np.sqrt(alphas) / (1. - alphas_cumprod)))
|
||||
|
||||
if self.parameterization == "eps":
|
||||
lvlb_weights = self.betas ** 2 / (
|
||||
2 * self.posterior_variance * to_torch(alphas) * (1 - self.alphas_cumprod))
|
||||
elif self.parameterization == "x0":
|
||||
lvlb_weights = 0.5 * np.sqrt(torch.Tensor(alphas_cumprod)) / (2. * 1 - torch.Tensor(alphas_cumprod))
|
||||
elif self.parameterization == "v":
|
||||
lvlb_weights = torch.ones_like(self.betas ** 2 / (
|
||||
2 * self.posterior_variance * to_torch(alphas) * (1 - self.alphas_cumprod)))
|
||||
else:
|
||||
raise NotImplementedError("mu not supported")
|
||||
# TODO how to choose this term
|
||||
lvlb_weights[0] = lvlb_weights[1]
|
||||
self.register_buffer('lvlb_weights', lvlb_weights, persistent=False)
|
||||
assert not torch.isnan(self.lvlb_weights).all()
|
||||
|
||||
@contextmanager
|
||||
def ema_scope(self, context=None):
|
||||
if self.use_ema:
|
||||
self.model_ema.store(self.model.parameters())
|
||||
self.model_ema.copy_to(self.model)
|
||||
if context is not None:
|
||||
mainlogger.info(f"{context}: Switched to EMA weights")
|
||||
try:
|
||||
yield None
|
||||
finally:
|
||||
if self.use_ema:
|
||||
self.model_ema.restore(self.model.parameters())
|
||||
if context is not None:
|
||||
mainlogger.info(f"{context}: Restored training weights")
|
||||
|
||||
def init_from_ckpt(self, path, ignore_keys=list(), only_model=False):
|
||||
sd = torch.load(path, map_location="cpu")
|
||||
if "state_dict" in list(sd.keys()):
|
||||
sd = sd["state_dict"]
|
||||
keys = list(sd.keys())
|
||||
for k in keys:
|
||||
for ik in ignore_keys:
|
||||
if k.startswith(ik):
|
||||
mainlogger.info("Deleting key {} from state_dict.".format(k))
|
||||
del sd[k]
|
||||
missing, unexpected = self.load_state_dict(sd, strict=False) if not only_model else self.model.load_state_dict(
|
||||
sd, strict=False)
|
||||
mainlogger.info(f"Restored from {path} with {len(missing)} missing and {len(unexpected)} unexpected keys")
|
||||
if len(missing) > 0:
|
||||
mainlogger.info(f"Missing Keys: {missing}")
|
||||
if len(unexpected) > 0:
|
||||
mainlogger.info(f"Unexpected Keys: {unexpected}")
|
||||
|
||||
def q_mean_variance(self, x_start, t):
|
||||
"""
|
||||
Get the distribution q(x_t | x_0).
|
||||
:param x_start: the [N x C x ...] tensor of noiseless inputs.
|
||||
:param t: the number of diffusion steps (minus 1). Here, 0 means one step.
|
||||
:return: A tuple (mean, variance, log_variance), all of x_start's shape.
|
||||
"""
|
||||
mean = (extract_into_tensor(self.sqrt_alphas_cumprod, t, x_start.shape) * x_start)
|
||||
variance = extract_into_tensor(1.0 - self.alphas_cumprod, t, x_start.shape)
|
||||
log_variance = extract_into_tensor(self.log_one_minus_alphas_cumprod, t, x_start.shape)
|
||||
return mean, variance, log_variance
|
||||
|
||||
def predict_start_from_noise(self, x_t, t, noise):
|
||||
return (
|
||||
extract_into_tensor(self.sqrt_recip_alphas_cumprod, t, x_t.shape) * x_t -
|
||||
extract_into_tensor(self.sqrt_recipm1_alphas_cumprod, t, x_t.shape) * noise
|
||||
)
|
||||
|
||||
def predict_start_from_z_and_v(self, x_t, t, v):
|
||||
# self.register_buffer('sqrt_alphas_cumprod', to_torch(np.sqrt(alphas_cumprod)))
|
||||
# self.register_buffer('sqrt_one_minus_alphas_cumprod', to_torch(np.sqrt(1. - alphas_cumprod)))
|
||||
return (
|
||||
extract_into_tensor(self.sqrt_alphas_cumprod, t, x_t.shape) * x_t -
|
||||
extract_into_tensor(self.sqrt_one_minus_alphas_cumprod, t, x_t.shape) * v
|
||||
)
|
||||
|
||||
def predict_eps_from_z_and_v(self, x_t, t, v):
|
||||
return (
|
||||
extract_into_tensor(self.sqrt_alphas_cumprod, t, x_t.shape) * v +
|
||||
extract_into_tensor(self.sqrt_one_minus_alphas_cumprod, t, x_t.shape) * x_t
|
||||
)
|
||||
|
||||
def q_posterior(self, x_start, x_t, t):
|
||||
posterior_mean = (
|
||||
extract_into_tensor(self.posterior_mean_coef1, t, x_t.shape) * x_start +
|
||||
extract_into_tensor(self.posterior_mean_coef2, t, x_t.shape) * x_t
|
||||
)
|
||||
posterior_variance = extract_into_tensor(self.posterior_variance, t, x_t.shape)
|
||||
posterior_log_variance_clipped = extract_into_tensor(self.posterior_log_variance_clipped, t, x_t.shape)
|
||||
return posterior_mean, posterior_variance, posterior_log_variance_clipped
|
||||
|
||||
def p_mean_variance(self, x, t, clip_denoised: bool):
|
||||
model_out = self.model(x, t)
|
||||
if self.parameterization == "eps":
|
||||
x_recon = self.predict_start_from_noise(x, t=t, noise=model_out)
|
||||
elif self.parameterization == "x0":
|
||||
x_recon = model_out
|
||||
if clip_denoised:
|
||||
x_recon.clamp_(-1., 1.)
|
||||
|
||||
model_mean, posterior_variance, posterior_log_variance = self.q_posterior(x_start=x_recon, x_t=x, t=t)
|
||||
return model_mean, posterior_variance, posterior_log_variance
|
||||
|
||||
@torch.no_grad()
|
||||
def p_sample(self, x, t, clip_denoised=True, repeat_noise=False):
|
||||
b, *_, device = *x.shape, x.device
|
||||
model_mean, _, model_log_variance = self.p_mean_variance(x=x, t=t, clip_denoised=clip_denoised)
|
||||
noise = noise_like(x.shape, device, repeat_noise)
|
||||
# no noise when t == 0
|
||||
nonzero_mask = (1 - (t == 0).float()).reshape(b, *((1,) * (len(x.shape) - 1)))
|
||||
return model_mean + nonzero_mask * (0.5 * model_log_variance).exp() * noise
|
||||
|
||||
@torch.no_grad()
|
||||
def p_sample_loop(self, shape, return_intermediates=False):
|
||||
device = self.betas.device
|
||||
b = shape[0]
|
||||
img = torch.randn(shape, device=device)
|
||||
intermediates = [img]
|
||||
for i in tqdm(reversed(range(0, self.num_timesteps)), desc='Sampling t', total=self.num_timesteps):
|
||||
img = self.p_sample(img, torch.full((b,), i, device=device, dtype=torch.long),
|
||||
clip_denoised=self.clip_denoised)
|
||||
if i % self.log_every_t == 0 or i == self.num_timesteps - 1:
|
||||
intermediates.append(img)
|
||||
if return_intermediates:
|
||||
return img, intermediates
|
||||
return img
|
||||
|
||||
@torch.no_grad()
|
||||
def sample(self, batch_size=16, return_intermediates=False):
|
||||
image_size = self.image_size
|
||||
channels = self.channels
|
||||
return self.p_sample_loop((batch_size, channels, image_size, image_size),
|
||||
return_intermediates=return_intermediates)
|
||||
|
||||
def q_sample(self, x_start, t, noise=None):
|
||||
noise = default(noise, lambda: torch.randn_like(x_start))
|
||||
return (extract_into_tensor(self.sqrt_alphas_cumprod, t, x_start.shape) * x_start +
|
||||
extract_into_tensor(self.sqrt_one_minus_alphas_cumprod, t, x_start.shape) * noise)
|
||||
|
||||
def get_v(self, x, noise, t):
|
||||
return (
|
||||
extract_into_tensor(self.sqrt_alphas_cumprod, t, x.shape) * noise -
|
||||
extract_into_tensor(self.sqrt_one_minus_alphas_cumprod, t, x.shape) * x
|
||||
)
|
||||
|
||||
def get_input(self, batch, k):
|
||||
x = batch[k]
|
||||
x = x.to(memory_format=torch.contiguous_format).float()
|
||||
return x
|
||||
|
||||
def _get_rows_from_list(self, samples):
|
||||
n_imgs_per_row = len(samples)
|
||||
denoise_grid = rearrange(samples, 'n b c h w -> b n c h w')
|
||||
denoise_grid = rearrange(denoise_grid, 'b n c h w -> (b n) c h w')
|
||||
denoise_grid = make_grid(denoise_grid, nrow=n_imgs_per_row)
|
||||
return denoise_grid
|
||||
|
||||
@torch.no_grad()
|
||||
def log_images(self, batch, N=8, n_row=2, sample=True, return_keys=None, **kwargs):
|
||||
log = dict()
|
||||
x = self.get_input(batch, self.first_stage_key)
|
||||
N = min(x.shape[0], N)
|
||||
n_row = min(x.shape[0], n_row)
|
||||
x = x.to(self.device)[:N]
|
||||
log["inputs"] = x
|
||||
|
||||
# get diffusion row
|
||||
diffusion_row = list()
|
||||
x_start = x[:n_row]
|
||||
|
||||
for t in range(self.num_timesteps):
|
||||
if t % self.log_every_t == 0 or t == self.num_timesteps - 1:
|
||||
t = repeat(torch.tensor([t]), '1 -> b', b=n_row)
|
||||
t = t.to(self.device).long()
|
||||
noise = torch.randn_like(x_start)
|
||||
x_noisy = self.q_sample(x_start=x_start, t=t, noise=noise)
|
||||
diffusion_row.append(x_noisy)
|
||||
|
||||
log["diffusion_row"] = self._get_rows_from_list(diffusion_row)
|
||||
|
||||
if sample:
|
||||
# get denoise row
|
||||
with self.ema_scope("Plotting"):
|
||||
samples, denoise_row = self.sample(batch_size=N, return_intermediates=True)
|
||||
|
||||
log["samples"] = samples
|
||||
log["denoise_row"] = self._get_rows_from_list(denoise_row)
|
||||
|
||||
if return_keys:
|
||||
if np.intersect1d(list(log.keys()), return_keys).shape[0] == 0:
|
||||
return log
|
||||
else:
|
||||
return {key: log[key] for key in return_keys}
|
||||
return log
|
||||
|
||||
|
||||
class LatentDiffusion(DDPM):
|
||||
"""main class"""
|
||||
def __init__(self,
|
||||
first_stage_config,
|
||||
cond_stage_config,
|
||||
num_timesteps_cond=None,
|
||||
cond_stage_key="caption",
|
||||
cond_stage_trainable=False,
|
||||
cond_stage_forward=None,
|
||||
conditioning_key=None,
|
||||
uncond_prob=0.2,
|
||||
uncond_type="empty_seq",
|
||||
scale_factor=1.0,
|
||||
scale_by_std=False,
|
||||
encoder_type="2d",
|
||||
only_model=False,
|
||||
noise_strength=0,
|
||||
use_dynamic_rescale=False,
|
||||
base_scale=0.7,
|
||||
turning_step=400,
|
||||
loop_video=False,
|
||||
fps_condition_type='fs',
|
||||
perframe_ae=False,
|
||||
*args, **kwargs):
|
||||
self.num_timesteps_cond = default(num_timesteps_cond, 1)
|
||||
self.scale_by_std = scale_by_std
|
||||
assert self.num_timesteps_cond <= kwargs['timesteps']
|
||||
# for backwards compatibility after implementation of DiffusionWrapper
|
||||
ckpt_path = kwargs.pop("ckpt_path", None)
|
||||
ignore_keys = kwargs.pop("ignore_keys", [])
|
||||
conditioning_key = default(conditioning_key, 'crossattn')
|
||||
super().__init__(conditioning_key=conditioning_key, *args, **kwargs)
|
||||
|
||||
self.cond_stage_trainable = cond_stage_trainable
|
||||
self.cond_stage_key = cond_stage_key
|
||||
self.noise_strength = noise_strength
|
||||
self.use_dynamic_rescale = use_dynamic_rescale
|
||||
self.loop_video = loop_video
|
||||
self.fps_condition_type = fps_condition_type
|
||||
self.perframe_ae = perframe_ae
|
||||
try:
|
||||
self.num_downs = len(first_stage_config.params.ddconfig.ch_mult) - 1
|
||||
except:
|
||||
self.num_downs = 0
|
||||
if not scale_by_std:
|
||||
self.scale_factor = scale_factor
|
||||
else:
|
||||
self.register_buffer('scale_factor', torch.tensor(scale_factor))
|
||||
|
||||
if use_dynamic_rescale:
|
||||
scale_arr1 = np.linspace(1.0, base_scale, turning_step)
|
||||
scale_arr2 = np.full(self.num_timesteps, base_scale)
|
||||
scale_arr = np.concatenate((scale_arr1, scale_arr2))
|
||||
to_torch = partial(torch.tensor, dtype=torch.float32)
|
||||
self.register_buffer('scale_arr', to_torch(scale_arr))
|
||||
|
||||
self.instantiate_first_stage(first_stage_config)
|
||||
self.instantiate_cond_stage(cond_stage_config)
|
||||
self.first_stage_config = first_stage_config
|
||||
self.cond_stage_config = cond_stage_config
|
||||
self.clip_denoised = False
|
||||
|
||||
self.cond_stage_forward = cond_stage_forward
|
||||
self.encoder_type = encoder_type
|
||||
assert(encoder_type in ["2d", "3d"])
|
||||
self.uncond_prob = uncond_prob
|
||||
self.classifier_free_guidance = True if uncond_prob > 0 else False
|
||||
assert(uncond_type in ["zero_embed", "empty_seq"])
|
||||
self.uncond_type = uncond_type
|
||||
|
||||
self.restarted_from_ckpt = False
|
||||
if ckpt_path is not None:
|
||||
self.init_from_ckpt(ckpt_path, ignore_keys, only_model=only_model)
|
||||
self.restarted_from_ckpt = True
|
||||
|
||||
|
||||
def make_cond_schedule(self, ):
|
||||
self.cond_ids = torch.full(size=(self.num_timesteps,), fill_value=self.num_timesteps - 1, dtype=torch.long)
|
||||
ids = torch.round(torch.linspace(0, self.num_timesteps - 1, self.num_timesteps_cond)).long()
|
||||
self.cond_ids[:self.num_timesteps_cond] = ids
|
||||
|
||||
def instantiate_first_stage(self, config):
|
||||
model = instantiate_from_config(config)
|
||||
self.first_stage_model = model.eval()
|
||||
self.first_stage_model.train = disabled_train
|
||||
for param in self.first_stage_model.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
def instantiate_cond_stage(self, config):
|
||||
if not self.cond_stage_trainable:
|
||||
model = instantiate_from_config(config)
|
||||
self.cond_stage_model = model.eval()
|
||||
self.cond_stage_model.train = disabled_train
|
||||
for param in self.cond_stage_model.parameters():
|
||||
param.requires_grad = False
|
||||
else:
|
||||
model = instantiate_from_config(config)
|
||||
self.cond_stage_model = model
|
||||
|
||||
def get_learned_conditioning(self, c):
|
||||
if self.cond_stage_forward is None:
|
||||
if hasattr(self.cond_stage_model, 'encode') and callable(self.cond_stage_model.encode):
|
||||
c = self.cond_stage_model.encode(c)
|
||||
if isinstance(c, DiagonalGaussianDistribution):
|
||||
c = c.mode()
|
||||
else:
|
||||
c = self.cond_stage_model(c)
|
||||
else:
|
||||
assert hasattr(self.cond_stage_model, self.cond_stage_forward)
|
||||
c = getattr(self.cond_stage_model, self.cond_stage_forward)(c)
|
||||
return c
|
||||
|
||||
def get_first_stage_encoding(self, encoder_posterior, noise=None):
|
||||
if isinstance(encoder_posterior, DiagonalGaussianDistribution):
|
||||
z = encoder_posterior.sample(noise=noise)
|
||||
elif isinstance(encoder_posterior, torch.Tensor):
|
||||
z = encoder_posterior
|
||||
else:
|
||||
raise NotImplementedError(f"encoder_posterior of type '{type(encoder_posterior)}' not yet implemented")
|
||||
return self.scale_factor * z
|
||||
|
||||
@torch.no_grad()
|
||||
def encode_first_stage(self, x):
|
||||
if self.encoder_type == "2d" and x.dim() == 5:
|
||||
b, _, t, _, _ = x.shape
|
||||
x = rearrange(x, 'b c t h w -> (b t) c h w')
|
||||
reshape_back = True
|
||||
else:
|
||||
reshape_back = False
|
||||
|
||||
## consume more GPU memory but faster
|
||||
if not self.perframe_ae:
|
||||
encoder_posterior = self.first_stage_model.encode(x)
|
||||
results = self.get_first_stage_encoding(encoder_posterior).detach()
|
||||
else: ## consume less GPU memory but slower
|
||||
results = []
|
||||
for index in range(x.shape[0]):
|
||||
frame_batch = self.first_stage_model.encode(x[index:index+1,:,:,:])
|
||||
frame_result = self.get_first_stage_encoding(frame_batch).detach()
|
||||
results.append(frame_result)
|
||||
results = torch.cat(results, dim=0)
|
||||
|
||||
if reshape_back:
|
||||
results = rearrange(results, '(b t) c h w -> b c t h w', b=b,t=t)
|
||||
|
||||
return results
|
||||
|
||||
def decode_core(self, z, **kwargs):
|
||||
if self.encoder_type == "2d" and z.dim() == 5:
|
||||
b, _, t, _, _ = z.shape
|
||||
z = rearrange(z, 'b c t h w -> (b t) c h w')
|
||||
reshape_back = True
|
||||
else:
|
||||
reshape_back = False
|
||||
|
||||
if not self.perframe_ae:
|
||||
z = 1. / self.scale_factor * z
|
||||
results = self.first_stage_model.decode(z, **kwargs)
|
||||
else:
|
||||
results = []
|
||||
for index in range(z.shape[0]):
|
||||
frame_z = 1. / self.scale_factor * z[index:index+1,:,:,:]
|
||||
frame_result = self.first_stage_model.decode(frame_z, **kwargs)
|
||||
results.append(frame_result)
|
||||
results = torch.cat(results, dim=0)
|
||||
|
||||
if reshape_back:
|
||||
results = rearrange(results, '(b t) c h w -> b c t h w', b=b,t=t)
|
||||
return results
|
||||
|
||||
@torch.no_grad()
|
||||
def decode_first_stage(self, z, **kwargs):
|
||||
return self.decode_core(z, **kwargs)
|
||||
|
||||
# same as above but without decorator
|
||||
def differentiable_decode_first_stage(self, z, **kwargs):
|
||||
return self.decode_core(z, **kwargs)
|
||||
|
||||
def forward(self, x, c, **kwargs):
|
||||
t = torch.randint(0, self.num_timesteps, (x.shape[0],), device=self.device).long()
|
||||
if self.use_dynamic_rescale:
|
||||
x = x * extract_into_tensor(self.scale_arr, t, x.shape)
|
||||
return self.p_losses(x, c, t, **kwargs)
|
||||
|
||||
def apply_model(self, x_noisy, t, cond, **kwargs):
|
||||
if isinstance(cond, dict):
|
||||
# hybrid case, cond is exptected to be a dict
|
||||
pass
|
||||
else:
|
||||
if not isinstance(cond, list):
|
||||
cond = [cond]
|
||||
key = 'c_concat' if self.model.conditioning_key == 'concat' else 'c_crossattn'
|
||||
cond = {key: cond}
|
||||
|
||||
x_recon = self.model(x_noisy, t, **cond, **kwargs)
|
||||
|
||||
if isinstance(x_recon, tuple):
|
||||
return x_recon[0]
|
||||
else:
|
||||
return x_recon
|
||||
|
||||
def _get_denoise_row_from_list(self, samples, desc=''):
|
||||
denoise_row = []
|
||||
for zd in tqdm(samples, desc=desc):
|
||||
denoise_row.append(self.decode_first_stage(zd.to(self.device)))
|
||||
n_log_timesteps = len(denoise_row)
|
||||
|
||||
denoise_row = torch.stack(denoise_row) # n_log_timesteps, b, C, H, W
|
||||
|
||||
if denoise_row.dim() == 5:
|
||||
denoise_grid = rearrange(denoise_row, 'n b c h w -> b n c h w')
|
||||
denoise_grid = rearrange(denoise_grid, 'b n c h w -> (b n) c h w')
|
||||
denoise_grid = make_grid(denoise_grid, nrow=n_log_timesteps)
|
||||
elif denoise_row.dim() == 6:
|
||||
# video, grid_size=[n_log_timesteps*bs, t]
|
||||
video_length = denoise_row.shape[3]
|
||||
denoise_grid = rearrange(denoise_row, 'n b c t h w -> b n c t h w')
|
||||
denoise_grid = rearrange(denoise_grid, 'b n c t h w -> (b n) c t h w')
|
||||
denoise_grid = rearrange(denoise_grid, 'n c t h w -> (n t) c h w')
|
||||
denoise_grid = make_grid(denoise_grid, nrow=video_length)
|
||||
else:
|
||||
raise ValueError
|
||||
|
||||
return denoise_grid
|
||||
|
||||
|
||||
def p_mean_variance(self, x, c, t, clip_denoised: bool, return_x0=False, score_corrector=None, corrector_kwargs=None, **kwargs):
|
||||
t_in = t
|
||||
model_out = self.apply_model(x, t_in, c, **kwargs)
|
||||
|
||||
if score_corrector is not None:
|
||||
assert self.parameterization == "eps"
|
||||
model_out = score_corrector.modify_score(self, model_out, x, t, c, **corrector_kwargs)
|
||||
|
||||
if self.parameterization == "eps":
|
||||
x_recon = self.predict_start_from_noise(x, t=t, noise=model_out)
|
||||
elif self.parameterization == "x0":
|
||||
x_recon = model_out
|
||||
else:
|
||||
raise NotImplementedError()
|
||||
|
||||
if clip_denoised:
|
||||
x_recon.clamp_(-1., 1.)
|
||||
|
||||
model_mean, posterior_variance, posterior_log_variance = self.q_posterior(x_start=x_recon, x_t=x, t=t)
|
||||
|
||||
if return_x0:
|
||||
return model_mean, posterior_variance, posterior_log_variance, x_recon
|
||||
else:
|
||||
return model_mean, posterior_variance, posterior_log_variance
|
||||
|
||||
@torch.no_grad()
|
||||
def p_sample(self, x, c, t, clip_denoised=False, repeat_noise=False, return_x0=False, \
|
||||
temperature=1., noise_dropout=0., score_corrector=None, corrector_kwargs=None, **kwargs):
|
||||
b, *_, device = *x.shape, x.device
|
||||
outputs = self.p_mean_variance(x=x, c=c, t=t, clip_denoised=clip_denoised, return_x0=return_x0, \
|
||||
score_corrector=score_corrector, corrector_kwargs=corrector_kwargs, **kwargs)
|
||||
if return_x0:
|
||||
model_mean, _, model_log_variance, x0 = outputs
|
||||
else:
|
||||
model_mean, _, model_log_variance = outputs
|
||||
|
||||
noise = noise_like(x.shape, device, repeat_noise) * temperature
|
||||
if noise_dropout > 0.:
|
||||
noise = torch.nn.functional.dropout(noise, p=noise_dropout)
|
||||
# no noise when t == 0
|
||||
nonzero_mask = (1 - (t == 0).float()).reshape(b, *((1,) * (len(x.shape) - 1)))
|
||||
|
||||
if return_x0:
|
||||
return model_mean + nonzero_mask * (0.5 * model_log_variance).exp() * noise, x0
|
||||
else:
|
||||
return model_mean + nonzero_mask * (0.5 * model_log_variance).exp() * noise
|
||||
|
||||
@torch.no_grad()
|
||||
def p_sample_loop(self, cond, shape, return_intermediates=False, x_T=None, verbose=True, callback=None, \
|
||||
timesteps=None, mask=None, x0=None, img_callback=None, start_T=None, log_every_t=None, **kwargs):
|
||||
|
||||
if not log_every_t:
|
||||
log_every_t = self.log_every_t
|
||||
device = self.betas.device
|
||||
b = shape[0]
|
||||
# sample an initial noise
|
||||
if x_T is None:
|
||||
img = torch.randn(shape, device=device)
|
||||
else:
|
||||
img = x_T
|
||||
|
||||
intermediates = [img]
|
||||
if timesteps is None:
|
||||
timesteps = self.num_timesteps
|
||||
if start_T is not None:
|
||||
timesteps = min(timesteps, start_T)
|
||||
|
||||
iterator = tqdm(reversed(range(0, timesteps)), desc='Sampling t', total=timesteps) if verbose else reversed(range(0, timesteps))
|
||||
|
||||
if mask is not None:
|
||||
assert x0 is not None
|
||||
assert x0.shape[2:3] == mask.shape[2:3] # spatial size has to match
|
||||
|
||||
for i in iterator:
|
||||
ts = torch.full((b,), i, device=device, dtype=torch.long)
|
||||
if self.shorten_cond_schedule:
|
||||
assert self.model.conditioning_key != 'hybrid'
|
||||
tc = self.cond_ids[ts].to(cond.device)
|
||||
cond = self.q_sample(x_start=cond, t=tc, noise=torch.randn_like(cond))
|
||||
|
||||
img = self.p_sample(img, cond, ts, clip_denoised=self.clip_denoised, **kwargs)
|
||||
if mask is not None:
|
||||
img_orig = self.q_sample(x0, ts)
|
||||
img = img_orig * mask + (1. - mask) * img
|
||||
|
||||
if i % log_every_t == 0 or i == timesteps - 1:
|
||||
intermediates.append(img)
|
||||
if callback: callback(i)
|
||||
if img_callback: img_callback(img, i)
|
||||
|
||||
if return_intermediates:
|
||||
return img, intermediates
|
||||
return img
|
||||
|
||||
|
||||
class LatentVisualDiffusion(LatentDiffusion):
|
||||
def __init__(self, img_cond_stage_config, image_proj_stage_config, freeze_embedder=True, *args, **kwargs):
|
||||
super().__init__(*args, **kwargs)
|
||||
self._init_embedder(img_cond_stage_config, freeze_embedder)
|
||||
self.image_proj_model = instantiate_from_config(image_proj_stage_config)
|
||||
|
||||
def _init_embedder(self, config, freeze=True):
|
||||
embedder = instantiate_from_config(config)
|
||||
if freeze:
|
||||
self.embedder = embedder.eval()
|
||||
self.embedder.train = disabled_train
|
||||
for param in self.embedder.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
|
||||
class DiffusionWrapper(pl.LightningModule):
|
||||
def __init__(self, diff_model_config, conditioning_key):
|
||||
super().__init__()
|
||||
self.diffusion_model = instantiate_from_config(diff_model_config)
|
||||
self.conditioning_key = conditioning_key
|
||||
|
||||
def forward(self, x, t, c_concat: list = None, c_crossattn: list = None,
|
||||
c_adm=None, s=None, mask=None, **kwargs):
|
||||
# temporal_context = fps is foNone
|
||||
if self.conditioning_key is None:
|
||||
out = self.diffusion_model(x, t)
|
||||
elif self.conditioning_key == 'concat':
|
||||
xc = torch.cat([x] + c_concat, dim=1)
|
||||
out = self.diffusion_model(xc, t, **kwargs)
|
||||
elif self.conditioning_key == 'crossattn':
|
||||
cc = torch.cat(c_crossattn, 1)
|
||||
out = self.diffusion_model(x, t, context=cc, **kwargs)
|
||||
elif self.conditioning_key == 'hybrid':
|
||||
## it is just right [b,c,t,h,w]: concatenate in channel dim
|
||||
xc = torch.cat([x] + c_concat, dim=1)
|
||||
cc = torch.cat(c_crossattn, 1)
|
||||
out = self.diffusion_model(xc, t, context=cc, **kwargs)
|
||||
elif self.conditioning_key == 'resblockcond':
|
||||
cc = c_crossattn[0]
|
||||
out = self.diffusion_model(x, t, context=cc)
|
||||
elif self.conditioning_key == 'adm':
|
||||
cc = c_crossattn[0]
|
||||
out = self.diffusion_model(x, t, y=cc)
|
||||
elif self.conditioning_key == 'hybrid-adm':
|
||||
assert c_adm is not None
|
||||
xc = torch.cat([x] + c_concat, dim=1)
|
||||
cc = torch.cat(c_crossattn, 1)
|
||||
out = self.diffusion_model(xc, t, context=cc, y=c_adm, **kwargs)
|
||||
elif self.conditioning_key == 'hybrid-time':
|
||||
assert s is not None
|
||||
xc = torch.cat([x] + c_concat, dim=1)
|
||||
cc = torch.cat(c_crossattn, 1)
|
||||
out = self.diffusion_model(xc, t, context=cc, s=s)
|
||||
elif self.conditioning_key == 'concat-time-mask':
|
||||
# assert s is not None
|
||||
xc = torch.cat([x] + c_concat, dim=1)
|
||||
out = self.diffusion_model(xc, t, context=None, s=s, mask=mask)
|
||||
elif self.conditioning_key == 'concat-adm-mask':
|
||||
# assert s is not None
|
||||
if c_concat is not None:
|
||||
xc = torch.cat([x] + c_concat, dim=1)
|
||||
else:
|
||||
xc = x
|
||||
out = self.diffusion_model(xc, t, context=None, y=s, mask=mask)
|
||||
elif self.conditioning_key == 'hybrid-adm-mask':
|
||||
cc = torch.cat(c_crossattn, 1)
|
||||
if c_concat is not None:
|
||||
xc = torch.cat([x] + c_concat, dim=1)
|
||||
else:
|
||||
xc = x
|
||||
out = self.diffusion_model(xc, t, context=cc, y=s, mask=mask)
|
||||
elif self.conditioning_key == 'hybrid-time-adm': # adm means y, e.g., class index
|
||||
# assert s is not None
|
||||
assert c_adm is not None
|
||||
xc = torch.cat([x] + c_concat, dim=1)
|
||||
cc = torch.cat(c_crossattn, 1)
|
||||
out = self.diffusion_model(xc, t, context=cc, s=s, y=c_adm)
|
||||
elif self.conditioning_key == 'crossattn-adm':
|
||||
assert c_adm is not None
|
||||
cc = torch.cat(c_crossattn, 1)
|
||||
out = self.diffusion_model(x, t, context=cc, y=c_adm)
|
||||
else:
|
||||
raise NotImplementedError()
|
||||
|
||||
return out
|
||||
@@ -0,0 +1,318 @@
|
||||
import numpy as np
|
||||
from tqdm import tqdm
|
||||
import torch
|
||||
from ....lvdm.models.utils_diffusion import make_ddim_sampling_parameters, make_ddim_timesteps, rescale_noise_cfg
|
||||
from ....lvdm.common import noise_like
|
||||
from ....lvdm.common import extract_into_tensor
|
||||
import copy
|
||||
import comfy.utils
|
||||
|
||||
class DDIMSampler(object):
|
||||
def __init__(self, model, schedule="linear", **kwargs):
|
||||
super().__init__()
|
||||
self.model = model
|
||||
self.ddpm_num_timesteps = model.num_timesteps
|
||||
self.schedule = schedule
|
||||
self.counter = 0
|
||||
|
||||
def register_buffer(self, name, attr):
|
||||
if type(attr) == torch.Tensor:
|
||||
if attr.device != torch.device("cuda"):
|
||||
attr = attr.to(torch.device("cuda"))
|
||||
setattr(self, name, attr)
|
||||
|
||||
def make_schedule(self, ddim_num_steps, ddim_discretize="uniform", ddim_eta=0., verbose=True):
|
||||
self.ddim_timesteps = make_ddim_timesteps(ddim_discr_method=ddim_discretize, num_ddim_timesteps=ddim_num_steps,
|
||||
num_ddpm_timesteps=self.ddpm_num_timesteps,verbose=verbose)
|
||||
alphas_cumprod = self.model.alphas_cumprod
|
||||
assert alphas_cumprod.shape[0] == self.ddpm_num_timesteps, 'alphas have to be defined for each timestep'
|
||||
to_torch = lambda x: x.clone().detach().to(torch.float32).to(self.model.device)
|
||||
|
||||
if self.model.use_dynamic_rescale:
|
||||
self.ddim_scale_arr = self.model.scale_arr[self.ddim_timesteps]
|
||||
self.ddim_scale_arr_prev = torch.cat([self.ddim_scale_arr[0:1], self.ddim_scale_arr[:-1]])
|
||||
|
||||
self.register_buffer('betas', to_torch(self.model.betas))
|
||||
self.register_buffer('alphas_cumprod', to_torch(alphas_cumprod))
|
||||
self.register_buffer('alphas_cumprod_prev', to_torch(self.model.alphas_cumprod_prev))
|
||||
|
||||
# calculations for diffusion q(x_t | x_{t-1}) and others
|
||||
self.register_buffer('sqrt_alphas_cumprod', to_torch(np.sqrt(alphas_cumprod.cpu())))
|
||||
self.register_buffer('sqrt_one_minus_alphas_cumprod', to_torch(np.sqrt(1. - alphas_cumprod.cpu())))
|
||||
self.register_buffer('log_one_minus_alphas_cumprod', to_torch(np.log(1. - alphas_cumprod.cpu())))
|
||||
self.register_buffer('sqrt_recip_alphas_cumprod', to_torch(np.sqrt(1. / alphas_cumprod.cpu())))
|
||||
self.register_buffer('sqrt_recipm1_alphas_cumprod', to_torch(np.sqrt(1. / alphas_cumprod.cpu() - 1)))
|
||||
|
||||
# ddim sampling parameters
|
||||
ddim_sigmas, ddim_alphas, ddim_alphas_prev = make_ddim_sampling_parameters(alphacums=alphas_cumprod.cpu(),
|
||||
ddim_timesteps=self.ddim_timesteps,
|
||||
eta=ddim_eta,verbose=verbose)
|
||||
self.register_buffer('ddim_sigmas', ddim_sigmas)
|
||||
self.register_buffer('ddim_alphas', ddim_alphas)
|
||||
self.register_buffer('ddim_alphas_prev', ddim_alphas_prev)
|
||||
self.register_buffer('ddim_sqrt_one_minus_alphas', np.sqrt(1. - ddim_alphas))
|
||||
sigmas_for_original_sampling_steps = ddim_eta * torch.sqrt(
|
||||
(1 - self.alphas_cumprod_prev) / (1 - self.alphas_cumprod) * (
|
||||
1 - self.alphas_cumprod / self.alphas_cumprod_prev))
|
||||
self.register_buffer('ddim_sigmas_for_original_num_steps', sigmas_for_original_sampling_steps)
|
||||
|
||||
@torch.no_grad()
|
||||
def sample(self,
|
||||
S,
|
||||
batch_size,
|
||||
shape,
|
||||
conditioning=None,
|
||||
callback=None,
|
||||
normals_sequence=None,
|
||||
img_callback=None,
|
||||
quantize_x0=False,
|
||||
eta=0.,
|
||||
mask=None,
|
||||
x0=None,
|
||||
temperature=1.,
|
||||
noise_dropout=0.,
|
||||
score_corrector=None,
|
||||
corrector_kwargs=None,
|
||||
verbose=True,
|
||||
schedule_verbose=False,
|
||||
x_T=None,
|
||||
log_every_t=100,
|
||||
unconditional_guidance_scale=1.,
|
||||
unconditional_conditioning=None,
|
||||
precision=None,
|
||||
fs=None,
|
||||
timestep_spacing='uniform', #uniform_trailing for starting from last timestep
|
||||
guidance_rescale=0.0,
|
||||
**kwargs
|
||||
):
|
||||
|
||||
# check condition bs
|
||||
if conditioning is not None:
|
||||
if isinstance(conditioning, dict):
|
||||
try:
|
||||
cbs = conditioning[list(conditioning.keys())[0]].shape[0]
|
||||
except:
|
||||
cbs = conditioning[list(conditioning.keys())[0]][0].shape[0]
|
||||
|
||||
if cbs != batch_size:
|
||||
print(f"Warning: Got {cbs} conditionings but batch-size is {batch_size}")
|
||||
else:
|
||||
if conditioning.shape[0] != batch_size:
|
||||
print(f"Warning: Got {conditioning.shape[0]} conditionings but batch-size is {batch_size}")
|
||||
|
||||
self.make_schedule(ddim_num_steps=S, ddim_discretize=timestep_spacing, ddim_eta=eta, verbose=schedule_verbose)
|
||||
|
||||
# make shape
|
||||
if len(shape) == 3:
|
||||
C, H, W = shape
|
||||
size = (batch_size, C, H, W)
|
||||
elif len(shape) == 4:
|
||||
C, T, H, W = shape
|
||||
size = (batch_size, C, T, H, W)
|
||||
|
||||
samples, intermediates = self.ddim_sampling(conditioning, size,
|
||||
callback=callback,
|
||||
img_callback=img_callback,
|
||||
quantize_denoised=quantize_x0,
|
||||
mask=mask, x0=x0,
|
||||
ddim_use_original_steps=False,
|
||||
noise_dropout=noise_dropout,
|
||||
temperature=temperature,
|
||||
score_corrector=score_corrector,
|
||||
corrector_kwargs=corrector_kwargs,
|
||||
x_T=x_T,
|
||||
log_every_t=log_every_t,
|
||||
unconditional_guidance_scale=unconditional_guidance_scale,
|
||||
unconditional_conditioning=unconditional_conditioning,
|
||||
verbose=verbose,
|
||||
precision=precision,
|
||||
fs=fs,
|
||||
guidance_rescale=guidance_rescale,
|
||||
**kwargs)
|
||||
return samples, intermediates
|
||||
|
||||
@torch.no_grad()
|
||||
def ddim_sampling(self, cond, shape,
|
||||
x_T=None, ddim_use_original_steps=False,
|
||||
callback=None, timesteps=None, quantize_denoised=False,
|
||||
mask=None, x0=None, img_callback=None, log_every_t=100,
|
||||
temperature=1., noise_dropout=0., score_corrector=None, corrector_kwargs=None,
|
||||
unconditional_guidance_scale=1., unconditional_conditioning=None, verbose=True,precision=None,fs=None,guidance_rescale=0.0,
|
||||
**kwargs):
|
||||
device = self.model.betas.device
|
||||
b = shape[0]
|
||||
if x_T is None:
|
||||
img = torch.randn(shape, device=device)
|
||||
else:
|
||||
img = x_T
|
||||
if precision is not None:
|
||||
if precision == 16:
|
||||
img = img.to(dtype=torch.float16)
|
||||
|
||||
if timesteps is None:
|
||||
timesteps = self.ddpm_num_timesteps if ddim_use_original_steps else self.ddim_timesteps
|
||||
elif timesteps is not None and not ddim_use_original_steps:
|
||||
subset_end = int(min(timesteps / self.ddim_timesteps.shape[0], 1) * self.ddim_timesteps.shape[0]) - 1
|
||||
timesteps = self.ddim_timesteps[:subset_end]
|
||||
|
||||
intermediates = {'x_inter': [img], 'pred_x0': [img]}
|
||||
time_range = reversed(range(0,timesteps)) if ddim_use_original_steps else np.flip(timesteps)
|
||||
total_steps = timesteps if ddim_use_original_steps else timesteps.shape[0]
|
||||
if verbose:
|
||||
iterator = tqdm(time_range, desc='DDIM Sampler', total=total_steps)
|
||||
else:
|
||||
iterator = time_range
|
||||
|
||||
clean_cond = kwargs.pop("clean_cond", False)
|
||||
|
||||
# cond_copy, unconditional_conditioning_copy = copy.deepcopy(cond), copy.deepcopy(unconditional_conditioning)
|
||||
pbar = comfy.utils.ProgressBar(total_steps)
|
||||
for i, step in enumerate(iterator):
|
||||
index = total_steps - i - 1
|
||||
ts = torch.full((b,), step, device=device, dtype=torch.long)
|
||||
|
||||
## use mask to blend noised original latent (img_orig) & new sampled latent (img)
|
||||
if mask is not None:
|
||||
assert x0 is not None
|
||||
if clean_cond:
|
||||
img_orig = x0
|
||||
else:
|
||||
img_orig = self.model.q_sample(x0, ts) # TODO: deterministic forward pass? <ddim inversion>
|
||||
img = img_orig * mask + (1. - mask) * img # keep original & modify use img
|
||||
|
||||
|
||||
|
||||
|
||||
outs = self.p_sample_ddim(img, cond, ts, index=index, use_original_steps=ddim_use_original_steps,
|
||||
quantize_denoised=quantize_denoised, temperature=temperature,
|
||||
noise_dropout=noise_dropout, score_corrector=score_corrector,
|
||||
corrector_kwargs=corrector_kwargs,
|
||||
unconditional_guidance_scale=unconditional_guidance_scale,
|
||||
unconditional_conditioning=unconditional_conditioning,
|
||||
mask=mask,x0=x0,fs=fs,guidance_rescale=guidance_rescale,
|
||||
**kwargs)
|
||||
|
||||
|
||||
img, pred_x0 = outs
|
||||
if callback: callback(i)
|
||||
if img_callback: img_callback(pred_x0, i)
|
||||
|
||||
if index % log_every_t == 0 or index == total_steps - 1:
|
||||
intermediates['x_inter'].append(img)
|
||||
intermediates['pred_x0'].append(pred_x0)
|
||||
pbar.update(1)
|
||||
return img, intermediates
|
||||
|
||||
@torch.no_grad()
|
||||
def p_sample_ddim(self, x, c, t, index, repeat_noise=False, use_original_steps=False, quantize_denoised=False,
|
||||
temperature=1., noise_dropout=0., score_corrector=None, corrector_kwargs=None,
|
||||
unconditional_guidance_scale=1., unconditional_conditioning=None,
|
||||
uc_type=None, conditional_guidance_scale_temporal=None,mask=None,x0=None,guidance_rescale=0.0,**kwargs):
|
||||
b, *_, device = *x.shape, x.device
|
||||
if x.dim() == 5:
|
||||
is_video = True
|
||||
else:
|
||||
is_video = False
|
||||
|
||||
if unconditional_conditioning is None or unconditional_guidance_scale == 1.:
|
||||
model_output = self.model.apply_model(x, t, c, **kwargs) # unet denoiser
|
||||
else:
|
||||
### do_classifier_free_guidance
|
||||
if isinstance(c, torch.Tensor) or isinstance(c, dict):
|
||||
e_t_cond = self.model.apply_model(x, t, c, **kwargs)
|
||||
e_t_uncond = self.model.apply_model(x, t, unconditional_conditioning, **kwargs)
|
||||
else:
|
||||
raise NotImplementedError
|
||||
|
||||
model_output = e_t_uncond + unconditional_guidance_scale * (e_t_cond - e_t_uncond)
|
||||
|
||||
if guidance_rescale > 0.0:
|
||||
model_output = rescale_noise_cfg(model_output, e_t_cond, guidance_rescale=guidance_rescale)
|
||||
|
||||
if self.model.parameterization == "v":
|
||||
e_t = self.model.predict_eps_from_z_and_v(x, t, model_output)
|
||||
else:
|
||||
e_t = model_output
|
||||
|
||||
if score_corrector is not None:
|
||||
assert self.model.parameterization == "eps", 'not implemented'
|
||||
e_t = score_corrector.modify_score(self.model, e_t, x, t, c, **corrector_kwargs)
|
||||
|
||||
alphas = self.model.alphas_cumprod if use_original_steps else self.ddim_alphas
|
||||
alphas_prev = self.model.alphas_cumprod_prev if use_original_steps else self.ddim_alphas_prev
|
||||
sqrt_one_minus_alphas = self.model.sqrt_one_minus_alphas_cumprod if use_original_steps else self.ddim_sqrt_one_minus_alphas
|
||||
# sigmas = self.model.ddim_sigmas_for_original_num_steps if use_original_steps else self.ddim_sigmas
|
||||
sigmas = self.ddim_sigmas_for_original_num_steps if use_original_steps else self.ddim_sigmas
|
||||
# select parameters corresponding to the currently considered timestep
|
||||
|
||||
if is_video:
|
||||
size = (b, 1, 1, 1, 1)
|
||||
else:
|
||||
size = (b, 1, 1, 1)
|
||||
a_t = torch.full(size, alphas[index], device=device)
|
||||
a_prev = torch.full(size, alphas_prev[index], device=device)
|
||||
sigma_t = torch.full(size, sigmas[index], device=device)
|
||||
sqrt_one_minus_at = torch.full(size, sqrt_one_minus_alphas[index],device=device)
|
||||
|
||||
# current prediction for x_0
|
||||
if self.model.parameterization != "v":
|
||||
pred_x0 = (x - sqrt_one_minus_at * e_t) / a_t.sqrt()
|
||||
else:
|
||||
pred_x0 = self.model.predict_start_from_z_and_v(x, t, model_output)
|
||||
|
||||
if self.model.use_dynamic_rescale:
|
||||
scale_t = torch.full(size, self.ddim_scale_arr[index], device=device)
|
||||
prev_scale_t = torch.full(size, self.ddim_scale_arr_prev[index], device=device)
|
||||
rescale = (prev_scale_t / scale_t)
|
||||
pred_x0 *= rescale
|
||||
|
||||
if quantize_denoised:
|
||||
pred_x0, _, *_ = self.model.first_stage_model.quantize(pred_x0)
|
||||
# direction pointing to x_t
|
||||
dir_xt = (1. - a_prev - sigma_t**2).sqrt() * e_t
|
||||
|
||||
noise = sigma_t * noise_like(x.shape, device, repeat_noise) * temperature
|
||||
if noise_dropout > 0.:
|
||||
noise = torch.nn.functional.dropout(noise, p=noise_dropout)
|
||||
|
||||
x_prev = a_prev.sqrt() * pred_x0 + dir_xt + noise
|
||||
|
||||
return x_prev, pred_x0
|
||||
|
||||
@torch.no_grad()
|
||||
def decode(self, x_latent, cond, t_start, unconditional_guidance_scale=1.0, unconditional_conditioning=None,
|
||||
use_original_steps=False, callback=None):
|
||||
|
||||
timesteps = np.arange(self.ddpm_num_timesteps) if use_original_steps else self.ddim_timesteps
|
||||
timesteps = timesteps[:t_start]
|
||||
|
||||
time_range = np.flip(timesteps)
|
||||
total_steps = timesteps.shape[0]
|
||||
print(f"Running DDIM Sampling with {total_steps} timesteps")
|
||||
|
||||
iterator = tqdm(time_range, desc='Decoding image', total=total_steps)
|
||||
x_dec = x_latent
|
||||
for i, step in enumerate(iterator):
|
||||
index = total_steps - i - 1
|
||||
ts = torch.full((x_latent.shape[0],), step, device=x_latent.device, dtype=torch.long)
|
||||
x_dec, _ = self.p_sample_ddim(x_dec, cond, ts, index=index, use_original_steps=use_original_steps,
|
||||
unconditional_guidance_scale=unconditional_guidance_scale,
|
||||
unconditional_conditioning=unconditional_conditioning)
|
||||
if callback: callback(i)
|
||||
return x_dec
|
||||
|
||||
@torch.no_grad()
|
||||
def stochastic_encode(self, x0, t, use_original_steps=False, noise=None):
|
||||
# fast, but does not allow for exact reconstruction
|
||||
# t serves as an index to gather the correct alphas
|
||||
if use_original_steps:
|
||||
sqrt_alphas_cumprod = self.sqrt_alphas_cumprod
|
||||
sqrt_one_minus_alphas_cumprod = self.sqrt_one_minus_alphas_cumprod
|
||||
else:
|
||||
sqrt_alphas_cumprod = torch.sqrt(self.ddim_alphas)
|
||||
sqrt_one_minus_alphas_cumprod = self.ddim_sqrt_one_minus_alphas
|
||||
|
||||
if noise is None:
|
||||
noise = torch.randn_like(x0)
|
||||
return (extract_into_tensor(sqrt_alphas_cumprod, t, x0.shape) * x0 +
|
||||
extract_into_tensor(sqrt_one_minus_alphas_cumprod, t, x0.shape) * noise)
|
||||
@@ -0,0 +1,323 @@
|
||||
import numpy as np
|
||||
from tqdm import tqdm
|
||||
import torch
|
||||
from ....lvdm.models.utils_diffusion import make_ddim_sampling_parameters, make_ddim_timesteps, rescale_noise_cfg
|
||||
from ....lvdm.common import noise_like
|
||||
from ....lvdm.common import extract_into_tensor
|
||||
import copy
|
||||
|
||||
|
||||
class DDIMSampler(object):
|
||||
def __init__(self, model, schedule="linear", **kwargs):
|
||||
super().__init__()
|
||||
self.model = model
|
||||
self.ddpm_num_timesteps = model.num_timesteps
|
||||
self.schedule = schedule
|
||||
self.counter = 0
|
||||
|
||||
def register_buffer(self, name, attr):
|
||||
if type(attr) == torch.Tensor:
|
||||
if attr.device != torch.device("cuda"):
|
||||
attr = attr.to(torch.device("cuda"))
|
||||
setattr(self, name, attr)
|
||||
|
||||
def make_schedule(self, ddim_num_steps, ddim_discretize="uniform", ddim_eta=0., verbose=True):
|
||||
self.ddim_timesteps = make_ddim_timesteps(ddim_discr_method=ddim_discretize, num_ddim_timesteps=ddim_num_steps,
|
||||
num_ddpm_timesteps=self.ddpm_num_timesteps,verbose=verbose)
|
||||
alphas_cumprod = self.model.alphas_cumprod
|
||||
assert alphas_cumprod.shape[0] == self.ddpm_num_timesteps, 'alphas have to be defined for each timestep'
|
||||
to_torch = lambda x: x.clone().detach().to(torch.float32).to(self.model.device)
|
||||
|
||||
if self.model.use_dynamic_rescale:
|
||||
self.ddim_scale_arr = self.model.scale_arr[self.ddim_timesteps]
|
||||
self.ddim_scale_arr_prev = torch.cat([self.ddim_scale_arr[0:1], self.ddim_scale_arr[:-1]])
|
||||
|
||||
self.register_buffer('betas', to_torch(self.model.betas))
|
||||
self.register_buffer('alphas_cumprod', to_torch(alphas_cumprod))
|
||||
self.register_buffer('alphas_cumprod_prev', to_torch(self.model.alphas_cumprod_prev))
|
||||
|
||||
# calculations for diffusion q(x_t | x_{t-1}) and others
|
||||
self.register_buffer('sqrt_alphas_cumprod', to_torch(np.sqrt(alphas_cumprod.cpu())))
|
||||
self.register_buffer('sqrt_one_minus_alphas_cumprod', to_torch(np.sqrt(1. - alphas_cumprod.cpu())))
|
||||
self.register_buffer('log_one_minus_alphas_cumprod', to_torch(np.log(1. - alphas_cumprod.cpu())))
|
||||
self.register_buffer('sqrt_recip_alphas_cumprod', to_torch(np.sqrt(1. / alphas_cumprod.cpu())))
|
||||
self.register_buffer('sqrt_recipm1_alphas_cumprod', to_torch(np.sqrt(1. / alphas_cumprod.cpu() - 1)))
|
||||
|
||||
# ddim sampling parameters
|
||||
ddim_sigmas, ddim_alphas, ddim_alphas_prev = make_ddim_sampling_parameters(alphacums=alphas_cumprod.cpu(),
|
||||
ddim_timesteps=self.ddim_timesteps,
|
||||
eta=ddim_eta,verbose=verbose)
|
||||
self.register_buffer('ddim_sigmas', ddim_sigmas)
|
||||
self.register_buffer('ddim_alphas', ddim_alphas)
|
||||
self.register_buffer('ddim_alphas_prev', ddim_alphas_prev)
|
||||
self.register_buffer('ddim_sqrt_one_minus_alphas', np.sqrt(1. - ddim_alphas))
|
||||
sigmas_for_original_sampling_steps = ddim_eta * torch.sqrt(
|
||||
(1 - self.alphas_cumprod_prev) / (1 - self.alphas_cumprod) * (
|
||||
1 - self.alphas_cumprod / self.alphas_cumprod_prev))
|
||||
self.register_buffer('ddim_sigmas_for_original_num_steps', sigmas_for_original_sampling_steps)
|
||||
|
||||
@torch.no_grad()
|
||||
def sample(self,
|
||||
S,
|
||||
batch_size,
|
||||
shape,
|
||||
conditioning=None,
|
||||
callback=None,
|
||||
normals_sequence=None,
|
||||
img_callback=None,
|
||||
quantize_x0=False,
|
||||
eta=0.,
|
||||
mask=None,
|
||||
x0=None,
|
||||
temperature=1.,
|
||||
noise_dropout=0.,
|
||||
score_corrector=None,
|
||||
corrector_kwargs=None,
|
||||
verbose=True,
|
||||
schedule_verbose=False,
|
||||
x_T=None,
|
||||
log_every_t=100,
|
||||
unconditional_guidance_scale=1.,
|
||||
unconditional_conditioning=None,
|
||||
precision=None,
|
||||
fs=None,
|
||||
timestep_spacing='uniform', #uniform_trailing for starting from last timestep
|
||||
guidance_rescale=0.0,
|
||||
# this has to come in the same format as the conditioning, # e.g. as encoded tokens, ...
|
||||
**kwargs
|
||||
):
|
||||
|
||||
# check condition bs
|
||||
if conditioning is not None:
|
||||
if isinstance(conditioning, dict):
|
||||
try:
|
||||
cbs = conditioning[list(conditioning.keys())[0]].shape[0]
|
||||
except:
|
||||
cbs = conditioning[list(conditioning.keys())[0]][0].shape[0]
|
||||
|
||||
if cbs != batch_size:
|
||||
print(f"Warning: Got {cbs} conditionings but batch-size is {batch_size}")
|
||||
else:
|
||||
if conditioning.shape[0] != batch_size:
|
||||
print(f"Warning: Got {conditioning.shape[0]} conditionings but batch-size is {batch_size}")
|
||||
|
||||
# print('==> timestep_spacing: ', timestep_spacing, guidance_rescale)
|
||||
self.make_schedule(ddim_num_steps=S, ddim_discretize=timestep_spacing, ddim_eta=eta, verbose=schedule_verbose)
|
||||
|
||||
# make shape
|
||||
if len(shape) == 3:
|
||||
C, H, W = shape
|
||||
size = (batch_size, C, H, W)
|
||||
elif len(shape) == 4:
|
||||
C, T, H, W = shape
|
||||
size = (batch_size, C, T, H, W)
|
||||
# print(f'Data shape for DDIM sampling is {size}, eta {eta}')
|
||||
|
||||
samples, intermediates = self.ddim_sampling(conditioning, size,
|
||||
callback=callback,
|
||||
img_callback=img_callback,
|
||||
quantize_denoised=quantize_x0,
|
||||
mask=mask, x0=x0,
|
||||
ddim_use_original_steps=False,
|
||||
noise_dropout=noise_dropout,
|
||||
temperature=temperature,
|
||||
score_corrector=score_corrector,
|
||||
corrector_kwargs=corrector_kwargs,
|
||||
x_T=x_T,
|
||||
log_every_t=log_every_t,
|
||||
unconditional_guidance_scale=unconditional_guidance_scale,
|
||||
unconditional_conditioning=unconditional_conditioning,
|
||||
verbose=verbose,
|
||||
precision=precision,
|
||||
fs=fs,
|
||||
guidance_rescale=guidance_rescale,
|
||||
**kwargs)
|
||||
return samples, intermediates
|
||||
|
||||
@torch.no_grad()
|
||||
def ddim_sampling(self, cond, shape,
|
||||
x_T=None, ddim_use_original_steps=False,
|
||||
callback=None, timesteps=None, quantize_denoised=False,
|
||||
mask=None, x0=None, img_callback=None, log_every_t=100,
|
||||
temperature=1., noise_dropout=0., score_corrector=None, corrector_kwargs=None,
|
||||
unconditional_guidance_scale=1., unconditional_conditioning=None, verbose=True,precision=None,fs=None,guidance_rescale=0.0,
|
||||
**kwargs):
|
||||
device = self.model.betas.device
|
||||
b = shape[0]
|
||||
if x_T is None:
|
||||
img = torch.randn(shape, device=device)
|
||||
else:
|
||||
img = x_T
|
||||
if precision is not None:
|
||||
if precision == 16:
|
||||
img = img.to(dtype=torch.float16)
|
||||
|
||||
|
||||
if timesteps is None:
|
||||
timesteps = self.ddpm_num_timesteps if ddim_use_original_steps else self.ddim_timesteps
|
||||
elif timesteps is not None and not ddim_use_original_steps:
|
||||
subset_end = int(min(timesteps / self.ddim_timesteps.shape[0], 1) * self.ddim_timesteps.shape[0]) - 1
|
||||
timesteps = self.ddim_timesteps[:subset_end]
|
||||
|
||||
intermediates = {'x_inter': [img], 'pred_x0': [img]}
|
||||
time_range = reversed(range(0,timesteps)) if ddim_use_original_steps else np.flip(timesteps)
|
||||
total_steps = timesteps if ddim_use_original_steps else timesteps.shape[0]
|
||||
if verbose:
|
||||
iterator = tqdm(time_range, desc='DDIM Sampler', total=total_steps)
|
||||
else:
|
||||
iterator = time_range
|
||||
|
||||
clean_cond = kwargs.pop("clean_cond", False)
|
||||
|
||||
# cond_copy, unconditional_conditioning_copy = copy.deepcopy(cond), copy.deepcopy(unconditional_conditioning)
|
||||
for i, step in enumerate(iterator):
|
||||
index = total_steps - i - 1
|
||||
ts = torch.full((b,), step, device=device, dtype=torch.long)
|
||||
|
||||
## use mask to blend noised original latent (img_orig) & new sampled latent (img)
|
||||
if mask is not None:
|
||||
assert x0 is not None
|
||||
if clean_cond:
|
||||
img_orig = x0
|
||||
else:
|
||||
img_orig = self.model.q_sample(x0, ts) # TODO: deterministic forward pass? <ddim inversion>
|
||||
img = img_orig * mask + (1. - mask) * img # keep original & modify use img
|
||||
|
||||
|
||||
|
||||
|
||||
outs = self.p_sample_ddim(img, cond, ts, index=index, use_original_steps=ddim_use_original_steps,
|
||||
quantize_denoised=quantize_denoised, temperature=temperature,
|
||||
noise_dropout=noise_dropout, score_corrector=score_corrector,
|
||||
corrector_kwargs=corrector_kwargs,
|
||||
unconditional_guidance_scale=unconditional_guidance_scale,
|
||||
unconditional_conditioning=unconditional_conditioning,
|
||||
mask=mask,x0=x0,fs=fs,guidance_rescale=guidance_rescale,
|
||||
**kwargs)
|
||||
|
||||
|
||||
|
||||
img, pred_x0 = outs
|
||||
if callback: callback(i)
|
||||
if img_callback: img_callback(pred_x0, i)
|
||||
|
||||
if index % log_every_t == 0 or index == total_steps - 1:
|
||||
intermediates['x_inter'].append(img)
|
||||
intermediates['pred_x0'].append(pred_x0)
|
||||
|
||||
return img, intermediates
|
||||
|
||||
@torch.no_grad()
|
||||
def p_sample_ddim(self, x, c, t, index, repeat_noise=False, use_original_steps=False, quantize_denoised=False,
|
||||
temperature=1., noise_dropout=0., score_corrector=None, corrector_kwargs=None,
|
||||
unconditional_guidance_scale=1., unconditional_conditioning=None,
|
||||
uc_type=None, cfg_img=None,mask=None,x0=None,guidance_rescale=0.0, **kwargs):
|
||||
b, *_, device = *x.shape, x.device
|
||||
if x.dim() == 5:
|
||||
is_video = True
|
||||
else:
|
||||
is_video = False
|
||||
if cfg_img is None:
|
||||
cfg_img = unconditional_guidance_scale
|
||||
|
||||
unconditional_conditioning_img_nonetext = kwargs['unconditional_conditioning_img_nonetext']
|
||||
|
||||
|
||||
if unconditional_conditioning is None or unconditional_guidance_scale == 1.:
|
||||
model_output = self.model.apply_model(x, t, c, **kwargs) # unet denoiser
|
||||
else:
|
||||
### with unconditional condition
|
||||
e_t_cond = self.model.apply_model(x, t, c, **kwargs)
|
||||
e_t_uncond = self.model.apply_model(x, t, unconditional_conditioning, **kwargs)
|
||||
e_t_uncond_img = self.model.apply_model(x, t, unconditional_conditioning_img_nonetext, **kwargs)
|
||||
# text cfg
|
||||
model_output = e_t_uncond + cfg_img * (e_t_uncond_img - e_t_uncond) + unconditional_guidance_scale * (e_t_cond - e_t_uncond_img)
|
||||
if guidance_rescale > 0.0:
|
||||
model_output = rescale_noise_cfg(model_output, e_t_cond, guidance_rescale=guidance_rescale)
|
||||
|
||||
if self.model.parameterization == "v":
|
||||
e_t = self.model.predict_eps_from_z_and_v(x, t, model_output)
|
||||
else:
|
||||
e_t = model_output
|
||||
|
||||
if score_corrector is not None:
|
||||
assert self.model.parameterization == "eps", 'not implemented'
|
||||
e_t = score_corrector.modify_score(self.model, e_t, x, t, c, **corrector_kwargs)
|
||||
|
||||
alphas = self.model.alphas_cumprod if use_original_steps else self.ddim_alphas
|
||||
alphas_prev = self.model.alphas_cumprod_prev if use_original_steps else self.ddim_alphas_prev
|
||||
sqrt_one_minus_alphas = self.model.sqrt_one_minus_alphas_cumprod if use_original_steps else self.ddim_sqrt_one_minus_alphas
|
||||
sigmas = self.ddim_sigmas_for_original_num_steps if use_original_steps else self.ddim_sigmas
|
||||
# select parameters corresponding to the currently considered timestep
|
||||
|
||||
if is_video:
|
||||
size = (b, 1, 1, 1, 1)
|
||||
else:
|
||||
size = (b, 1, 1, 1)
|
||||
a_t = torch.full(size, alphas[index], device=device)
|
||||
a_prev = torch.full(size, alphas_prev[index], device=device)
|
||||
sigma_t = torch.full(size, sigmas[index], device=device)
|
||||
sqrt_one_minus_at = torch.full(size, sqrt_one_minus_alphas[index],device=device)
|
||||
|
||||
# current prediction for x_0
|
||||
if self.model.parameterization != "v":
|
||||
pred_x0 = (x - sqrt_one_minus_at * e_t) / a_t.sqrt()
|
||||
else:
|
||||
pred_x0 = self.model.predict_start_from_z_and_v(x, t, model_output)
|
||||
|
||||
if self.model.use_dynamic_rescale:
|
||||
scale_t = torch.full(size, self.ddim_scale_arr[index], device=device)
|
||||
prev_scale_t = torch.full(size, self.ddim_scale_arr_prev[index], device=device)
|
||||
rescale = (prev_scale_t / scale_t)
|
||||
pred_x0 *= rescale
|
||||
|
||||
if quantize_denoised:
|
||||
pred_x0, _, *_ = self.model.first_stage_model.quantize(pred_x0)
|
||||
# direction pointing to x_t
|
||||
dir_xt = (1. - a_prev - sigma_t**2).sqrt() * e_t
|
||||
|
||||
noise = sigma_t * noise_like(x.shape, device, repeat_noise) * temperature
|
||||
if noise_dropout > 0.:
|
||||
noise = torch.nn.functional.dropout(noise, p=noise_dropout)
|
||||
|
||||
x_prev = a_prev.sqrt() * pred_x0 + dir_xt + noise
|
||||
|
||||
return x_prev, pred_x0
|
||||
|
||||
@torch.no_grad()
|
||||
def decode(self, x_latent, cond, t_start, unconditional_guidance_scale=1.0, unconditional_conditioning=None,
|
||||
use_original_steps=False, callback=None):
|
||||
|
||||
timesteps = np.arange(self.ddpm_num_timesteps) if use_original_steps else self.ddim_timesteps
|
||||
timesteps = timesteps[:t_start]
|
||||
|
||||
time_range = np.flip(timesteps)
|
||||
total_steps = timesteps.shape[0]
|
||||
print(f"Running DDIM Sampling with {total_steps} timesteps")
|
||||
|
||||
iterator = tqdm(time_range, desc='Decoding image', total=total_steps)
|
||||
x_dec = x_latent
|
||||
for i, step in enumerate(iterator):
|
||||
index = total_steps - i - 1
|
||||
ts = torch.full((x_latent.shape[0],), step, device=x_latent.device, dtype=torch.long)
|
||||
x_dec, _ = self.p_sample_ddim(x_dec, cond, ts, index=index, use_original_steps=use_original_steps,
|
||||
unconditional_guidance_scale=unconditional_guidance_scale,
|
||||
unconditional_conditioning=unconditional_conditioning)
|
||||
if callback: callback(i)
|
||||
return x_dec
|
||||
|
||||
@torch.no_grad()
|
||||
def stochastic_encode(self, x0, t, use_original_steps=False, noise=None):
|
||||
# fast, but does not allow for exact reconstruction
|
||||
# t serves as an index to gather the correct alphas
|
||||
if use_original_steps:
|
||||
sqrt_alphas_cumprod = self.sqrt_alphas_cumprod
|
||||
sqrt_one_minus_alphas_cumprod = self.sqrt_one_minus_alphas_cumprod
|
||||
else:
|
||||
sqrt_alphas_cumprod = torch.sqrt(self.ddim_alphas)
|
||||
sqrt_one_minus_alphas_cumprod = self.ddim_sqrt_one_minus_alphas
|
||||
|
||||
if noise is None:
|
||||
noise = torch.randn_like(x0)
|
||||
return (extract_into_tensor(sqrt_alphas_cumprod, t, x0.shape) * x0 +
|
||||
extract_into_tensor(sqrt_one_minus_alphas_cumprod, t, x0.shape) * noise)
|
||||
@@ -0,0 +1,158 @@
|
||||
import math
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from einops import repeat
|
||||
|
||||
|
||||
def timestep_embedding(timesteps, dim, max_period=10000, repeat_only=False):
|
||||
"""
|
||||
Create sinusoidal timestep embeddings.
|
||||
:param timesteps: a 1-D Tensor of N indices, one per batch element.
|
||||
These may be fractional.
|
||||
:param dim: the dimension of the output.
|
||||
:param max_period: controls the minimum frequency of the embeddings.
|
||||
:return: an [N x dim] Tensor of positional embeddings.
|
||||
"""
|
||||
if not repeat_only:
|
||||
half = dim // 2
|
||||
freqs = torch.exp(
|
||||
-math.log(max_period) * torch.arange(start=0, end=half, dtype=torch.float32) / half
|
||||
).to(device=timesteps.device)
|
||||
args = timesteps[:, None].float() * freqs[None]
|
||||
embedding = torch.cat([torch.cos(args), torch.sin(args)], dim=-1)
|
||||
if dim % 2:
|
||||
embedding = torch.cat([embedding, torch.zeros_like(embedding[:, :1])], dim=-1)
|
||||
else:
|
||||
embedding = repeat(timesteps, 'b -> b d', d=dim)
|
||||
return embedding
|
||||
|
||||
|
||||
def make_beta_schedule(schedule, n_timestep, linear_start=1e-4, linear_end=2e-2, cosine_s=8e-3):
|
||||
if schedule == "linear":
|
||||
betas = (
|
||||
torch.linspace(linear_start ** 0.5, linear_end ** 0.5, n_timestep, dtype=torch.float64) ** 2
|
||||
)
|
||||
|
||||
elif schedule == "cosine":
|
||||
timesteps = (
|
||||
torch.arange(n_timestep + 1, dtype=torch.float64) / n_timestep + cosine_s
|
||||
)
|
||||
alphas = timesteps / (1 + cosine_s) * np.pi / 2
|
||||
alphas = torch.cos(alphas).pow(2)
|
||||
alphas = alphas / alphas[0]
|
||||
betas = 1 - alphas[1:] / alphas[:-1]
|
||||
betas = np.clip(betas, a_min=0, a_max=0.999)
|
||||
|
||||
elif schedule == "sqrt_linear":
|
||||
betas = torch.linspace(linear_start, linear_end, n_timestep, dtype=torch.float64)
|
||||
elif schedule == "sqrt":
|
||||
betas = torch.linspace(linear_start, linear_end, n_timestep, dtype=torch.float64) ** 0.5
|
||||
else:
|
||||
raise ValueError(f"schedule '{schedule}' unknown.")
|
||||
return betas.numpy()
|
||||
|
||||
|
||||
def make_ddim_timesteps(ddim_discr_method, num_ddim_timesteps, num_ddpm_timesteps, verbose=True):
|
||||
if ddim_discr_method == 'uniform':
|
||||
c = num_ddpm_timesteps // num_ddim_timesteps
|
||||
ddim_timesteps = np.asarray(list(range(0, num_ddpm_timesteps, c)))
|
||||
steps_out = ddim_timesteps + 1
|
||||
elif ddim_discr_method == 'uniform_trailing':
|
||||
c = num_ddpm_timesteps / num_ddim_timesteps
|
||||
ddim_timesteps = np.flip(np.round(np.arange(num_ddpm_timesteps, 0, -c))).astype(np.int64)
|
||||
steps_out = ddim_timesteps - 1
|
||||
elif ddim_discr_method == 'quad':
|
||||
ddim_timesteps = ((np.linspace(0, np.sqrt(num_ddpm_timesteps * .8), num_ddim_timesteps)) ** 2).astype(int)
|
||||
steps_out = ddim_timesteps + 1
|
||||
else:
|
||||
raise NotImplementedError(f'There is no ddim discretization method called "{ddim_discr_method}"')
|
||||
|
||||
# assert ddim_timesteps.shape[0] == num_ddim_timesteps
|
||||
# add one to get the final alpha values right (the ones from first scale to data during sampling)
|
||||
# steps_out = ddim_timesteps + 1
|
||||
if verbose:
|
||||
print(f'Selected timesteps for ddim sampler: {steps_out}')
|
||||
return steps_out
|
||||
|
||||
|
||||
def make_ddim_sampling_parameters(alphacums, ddim_timesteps, eta, verbose=True):
|
||||
# select alphas for computing the variance schedule
|
||||
# print(f'ddim_timesteps={ddim_timesteps}, len_alphacums={len(alphacums)}')
|
||||
alphas = alphacums[ddim_timesteps]
|
||||
alphas_prev = np.asarray([alphacums[0]] + alphacums[ddim_timesteps[:-1]].tolist())
|
||||
|
||||
# according the the formula provided in https://arxiv.org/abs/2010.02502
|
||||
sigmas = eta * np.sqrt((1 - alphas_prev) / (1 - alphas) * (1 - alphas / alphas_prev))
|
||||
if verbose:
|
||||
print(f'Selected alphas for ddim sampler: a_t: {alphas}; a_(t-1): {alphas_prev}')
|
||||
print(f'For the chosen value of eta, which is {eta}, '
|
||||
f'this results in the following sigma_t schedule for ddim sampler {sigmas}')
|
||||
return sigmas, alphas, alphas_prev
|
||||
|
||||
|
||||
def betas_for_alpha_bar(num_diffusion_timesteps, alpha_bar, max_beta=0.999):
|
||||
"""
|
||||
Create a beta schedule that discretizes the given alpha_t_bar function,
|
||||
which defines the cumulative product of (1-beta) over time from t = [0,1].
|
||||
:param num_diffusion_timesteps: the number of betas to produce.
|
||||
:param alpha_bar: a lambda that takes an argument t from 0 to 1 and
|
||||
produces the cumulative product of (1-beta) up to that
|
||||
part of the diffusion process.
|
||||
:param max_beta: the maximum beta to use; use values lower than 1 to
|
||||
prevent singularities.
|
||||
"""
|
||||
betas = []
|
||||
for i in range(num_diffusion_timesteps):
|
||||
t1 = i / num_diffusion_timesteps
|
||||
t2 = (i + 1) / num_diffusion_timesteps
|
||||
betas.append(min(1 - alpha_bar(t2) / alpha_bar(t1), max_beta))
|
||||
return np.array(betas)
|
||||
|
||||
def rescale_zero_terminal_snr(betas):
|
||||
"""
|
||||
Rescales betas to have zero terminal SNR Based on https://arxiv.org/pdf/2305.08891.pdf (Algorithm 1)
|
||||
|
||||
Args:
|
||||
betas (`numpy.ndarray`):
|
||||
the betas that the scheduler is being initialized with.
|
||||
|
||||
Returns:
|
||||
`numpy.ndarray`: rescaled betas with zero terminal SNR
|
||||
"""
|
||||
# Convert betas to alphas_bar_sqrt
|
||||
alphas = 1.0 - betas
|
||||
alphas_cumprod = np.cumprod(alphas, axis=0)
|
||||
alphas_bar_sqrt = np.sqrt(alphas_cumprod)
|
||||
|
||||
# Store old values.
|
||||
alphas_bar_sqrt_0 = alphas_bar_sqrt[0].copy()
|
||||
alphas_bar_sqrt_T = alphas_bar_sqrt[-1].copy()
|
||||
|
||||
# Shift so the last timestep is zero.
|
||||
alphas_bar_sqrt -= alphas_bar_sqrt_T
|
||||
|
||||
# Scale so the first timestep is back to the old value.
|
||||
alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T)
|
||||
|
||||
# Convert alphas_bar_sqrt to betas
|
||||
alphas_bar = alphas_bar_sqrt**2 # Revert sqrt
|
||||
alphas = alphas_bar[1:] / alphas_bar[:-1] # Revert cumprod
|
||||
alphas = np.concatenate([alphas_bar[0:1], alphas])
|
||||
betas = 1 - alphas
|
||||
|
||||
return betas
|
||||
|
||||
|
||||
def rescale_noise_cfg(noise_cfg, noise_pred_text, guidance_rescale=0.0):
|
||||
"""
|
||||
Rescale `noise_cfg` according to `guidance_rescale`. Based on findings of [Common Diffusion Noise Schedules and
|
||||
Sample Steps are Flawed](https://arxiv.org/pdf/2305.08891.pdf). See Section 3.4
|
||||
"""
|
||||
std_text = noise_pred_text.std(dim=list(range(1, noise_pred_text.ndim)), keepdim=True)
|
||||
std_cfg = noise_cfg.std(dim=list(range(1, noise_cfg.ndim)), keepdim=True)
|
||||
# rescale the results from guidance (fixes overexposure)
|
||||
noise_pred_rescaled = noise_cfg * (std_text / std_cfg)
|
||||
# mix with the original results from guidance by factor guidance_rescale to avoid "plain looking" images
|
||||
noise_cfg = guidance_rescale * noise_pred_rescaled + (1 - guidance_rescale) * noise_cfg
|
||||
return noise_cfg
|
||||
@@ -0,0 +1,521 @@
|
||||
import torch
|
||||
from torch import nn, einsum
|
||||
import torch.nn.functional as F
|
||||
from einops import rearrange, repeat
|
||||
from functools import partial
|
||||
try:
|
||||
import xformers
|
||||
import xformers.ops
|
||||
XFORMERS_IS_AVAILBLE = True
|
||||
except:
|
||||
XFORMERS_IS_AVAILBLE = False
|
||||
from ...lvdm.common import (
|
||||
checkpoint,
|
||||
exists,
|
||||
default,
|
||||
)
|
||||
from ...lvdm.basics import zero_module
|
||||
|
||||
class Conv2d(torch.nn.Conv2d):
|
||||
def reset_parameters(self):
|
||||
return None
|
||||
|
||||
class Linear(torch.nn.Linear):
|
||||
def reset_parameters(self):
|
||||
return None
|
||||
|
||||
class RelativePosition(nn.Module):
|
||||
""" https://github.com/evelinehong/Transformer_Relative_Position_PyTorch/blob/master/relative_position.py """
|
||||
|
||||
def __init__(self, num_units, max_relative_position):
|
||||
super().__init__()
|
||||
self.num_units = num_units
|
||||
self.max_relative_position = max_relative_position
|
||||
self.embeddings_table = nn.Parameter(torch.Tensor(max_relative_position * 2 + 1, num_units))
|
||||
nn.init.xavier_uniform_(self.embeddings_table)
|
||||
|
||||
def forward(self, length_q, length_k):
|
||||
device = self.embeddings_table.device
|
||||
range_vec_q = torch.arange(length_q, device=device)
|
||||
range_vec_k = torch.arange(length_k, device=device)
|
||||
distance_mat = range_vec_k[None, :] - range_vec_q[:, None]
|
||||
distance_mat_clipped = torch.clamp(distance_mat, -self.max_relative_position, self.max_relative_position)
|
||||
final_mat = distance_mat_clipped + self.max_relative_position
|
||||
final_mat = final_mat.long()
|
||||
embeddings = self.embeddings_table[final_mat]
|
||||
return embeddings
|
||||
|
||||
|
||||
class CrossAttention(nn.Module):
|
||||
|
||||
def __init__(self, query_dim, context_dim=None, heads=8, dim_head=64, dropout=0.,
|
||||
relative_position=False, temporal_length=None, video_length=None, image_cross_attention=False, image_cross_attention_scale=1.0, image_cross_attention_scale_learnable=False, text_context_len=77):
|
||||
super().__init__()
|
||||
inner_dim = dim_head * heads
|
||||
context_dim = default(context_dim, query_dim)
|
||||
|
||||
self.scale = dim_head**-0.5
|
||||
self.heads = heads
|
||||
self.dim_head = dim_head
|
||||
self.to_q = Linear(query_dim, inner_dim, bias=False)
|
||||
self.to_k = Linear(context_dim, inner_dim, bias=False)
|
||||
self.to_v = Linear(context_dim, inner_dim, bias=False)
|
||||
|
||||
self.to_out = nn.Sequential(Linear(inner_dim, query_dim), nn.Dropout(dropout))
|
||||
|
||||
self.relative_position = relative_position
|
||||
if self.relative_position:
|
||||
assert(temporal_length is not None)
|
||||
self.relative_position_k = RelativePosition(num_units=dim_head, max_relative_position=temporal_length)
|
||||
self.relative_position_v = RelativePosition(num_units=dim_head, max_relative_position=temporal_length)
|
||||
else:
|
||||
## only used for spatial attention, while NOT for temporal attention
|
||||
if XFORMERS_IS_AVAILBLE and temporal_length is None:
|
||||
self.forward = self.efficient_forward
|
||||
|
||||
self.video_length = video_length
|
||||
self.image_cross_attention = image_cross_attention
|
||||
self.image_cross_attention_scale = image_cross_attention_scale
|
||||
self.text_context_len = text_context_len
|
||||
self.image_cross_attention_scale_learnable = image_cross_attention_scale_learnable
|
||||
if self.image_cross_attention:
|
||||
self.to_k_ip = Linear(context_dim, inner_dim, bias=False)
|
||||
self.to_v_ip = Linear(context_dim, inner_dim, bias=False)
|
||||
if image_cross_attention_scale_learnable:
|
||||
self.register_parameter('alpha', nn.Parameter(torch.tensor(0.)) )
|
||||
|
||||
|
||||
def forward(self, x, context=None, mask=None):
|
||||
spatial_self_attn = (context is None)
|
||||
k_ip, v_ip, out_ip = None, None, None
|
||||
|
||||
h = self.heads
|
||||
q = self.to_q(x)
|
||||
context = default(context, x)
|
||||
|
||||
if self.image_cross_attention and not spatial_self_attn:
|
||||
context, context_image = context[:,:self.text_context_len,:], context[:,self.text_context_len:,:]
|
||||
k = self.to_k(context)
|
||||
v = self.to_v(context)
|
||||
k_ip = self.to_k_ip(context_image)
|
||||
v_ip = self.to_v_ip(context_image)
|
||||
else:
|
||||
if not spatial_self_attn:
|
||||
context = context[:,:self.text_context_len,:]
|
||||
k = self.to_k(context)
|
||||
v = self.to_v(context)
|
||||
|
||||
q, k, v = map(lambda t: rearrange(t, 'b n (h d) -> (b h) n d', h=h), (q, k, v))
|
||||
|
||||
sim = torch.einsum('b i d, b j d -> b i j', q, k) * self.scale
|
||||
if self.relative_position:
|
||||
len_q, len_k, len_v = q.shape[1], k.shape[1], v.shape[1]
|
||||
k2 = self.relative_position_k(len_q, len_k)
|
||||
sim2 = einsum('b t d, t s d -> b t s', q, k2) * self.scale # TODO check
|
||||
sim += sim2
|
||||
del k
|
||||
|
||||
if exists(mask):
|
||||
## feasible for causal attention mask only
|
||||
max_neg_value = -torch.finfo(sim.dtype).max
|
||||
mask = repeat(mask, 'b i j -> (b h) i j', h=h)
|
||||
sim.masked_fill_(~(mask>0.5), max_neg_value)
|
||||
|
||||
# attention, what we cannot get enough of
|
||||
sim = sim.softmax(dim=-1)
|
||||
|
||||
out = torch.einsum('b i j, b j d -> b i d', sim, v)
|
||||
if self.relative_position:
|
||||
v2 = self.relative_position_v(len_q, len_v)
|
||||
out2 = einsum('b t s, t s d -> b t d', sim, v2) # TODO check
|
||||
out += out2
|
||||
out = rearrange(out, '(b h) n d -> b n (h d)', h=h)
|
||||
|
||||
|
||||
## for image cross-attention
|
||||
if k_ip is not None:
|
||||
k_ip, v_ip = map(lambda t: rearrange(t, 'b n (h d) -> (b h) n d', h=h), (k_ip, v_ip))
|
||||
sim_ip = torch.einsum('b i d, b j d -> b i j', q, k_ip) * self.scale
|
||||
del k_ip
|
||||
sim_ip = sim_ip.softmax(dim=-1)
|
||||
out_ip = torch.einsum('b i j, b j d -> b i d', sim_ip, v_ip)
|
||||
out_ip = rearrange(out_ip, '(b h) n d -> b n (h d)', h=h)
|
||||
|
||||
|
||||
if out_ip is not None:
|
||||
if self.image_cross_attention_scale_learnable:
|
||||
out = out + self.image_cross_attention_scale * out_ip * (torch.tanh(self.alpha)+1)
|
||||
else:
|
||||
out = out + self.image_cross_attention_scale * out_ip
|
||||
|
||||
return self.to_out(out)
|
||||
|
||||
def efficient_forward(self, x, context=None, mask=None):
|
||||
spatial_self_attn = (context is None)
|
||||
k_ip, v_ip, out_ip = None, None, None
|
||||
|
||||
q = self.to_q(x)
|
||||
context = default(context, x)
|
||||
|
||||
if self.image_cross_attention and not spatial_self_attn:
|
||||
context, context_image = context[:,:self.text_context_len,:], context[:,self.text_context_len:,:]
|
||||
k = self.to_k(context)
|
||||
v = self.to_v(context)
|
||||
k_ip = self.to_k_ip(context_image)
|
||||
v_ip = self.to_v_ip(context_image)
|
||||
else:
|
||||
if not spatial_self_attn:
|
||||
context = context[:,:self.text_context_len,:]
|
||||
k = self.to_k(context)
|
||||
v = self.to_v(context)
|
||||
|
||||
b, _, _ = q.shape
|
||||
q, k, v = map(
|
||||
lambda t: t.unsqueeze(3)
|
||||
.reshape(b, t.shape[1], self.heads, self.dim_head)
|
||||
.permute(0, 2, 1, 3)
|
||||
.reshape(b * self.heads, t.shape[1], self.dim_head)
|
||||
.contiguous(),
|
||||
(q, k, v),
|
||||
)
|
||||
# actually compute the attention, what we cannot get enough of
|
||||
out = xformers.ops.memory_efficient_attention(q, k, v, attn_bias=None, op=None)
|
||||
|
||||
## for image cross-attention
|
||||
if k_ip is not None:
|
||||
k_ip, v_ip = map(
|
||||
lambda t: t.unsqueeze(3)
|
||||
.reshape(b, t.shape[1], self.heads, self.dim_head)
|
||||
.permute(0, 2, 1, 3)
|
||||
.reshape(b * self.heads, t.shape[1], self.dim_head)
|
||||
.contiguous(),
|
||||
(k_ip, v_ip),
|
||||
)
|
||||
out_ip = xformers.ops.memory_efficient_attention(q, k_ip, v_ip, attn_bias=None, op=None)
|
||||
out_ip = (
|
||||
out_ip.unsqueeze(0)
|
||||
.reshape(b, self.heads, out.shape[1], self.dim_head)
|
||||
.permute(0, 2, 1, 3)
|
||||
.reshape(b, out.shape[1], self.heads * self.dim_head)
|
||||
)
|
||||
|
||||
if exists(mask):
|
||||
raise NotImplementedError
|
||||
out = (
|
||||
out.unsqueeze(0)
|
||||
.reshape(b, self.heads, out.shape[1], self.dim_head)
|
||||
.permute(0, 2, 1, 3)
|
||||
.reshape(b, out.shape[1], self.heads * self.dim_head)
|
||||
)
|
||||
if out_ip is not None:
|
||||
if self.image_cross_attention_scale_learnable:
|
||||
out = out + self.image_cross_attention_scale * out_ip * (torch.tanh(self.alpha)+1)
|
||||
else:
|
||||
out = out + self.image_cross_attention_scale * out_ip
|
||||
|
||||
return self.to_out(out)
|
||||
|
||||
|
||||
class BasicTransformerBlock(nn.Module):
|
||||
|
||||
def __init__(self, dim, n_heads, d_head, dropout=0., context_dim=None, gated_ff=True, checkpoint=True,
|
||||
disable_self_attn=False, attention_cls=None, video_length=None, image_cross_attention=False, image_cross_attention_scale=1.0, image_cross_attention_scale_learnable=False, text_context_len=77):
|
||||
super().__init__()
|
||||
attn_cls = CrossAttention if attention_cls is None else attention_cls
|
||||
self.disable_self_attn = disable_self_attn
|
||||
self.attn1 = attn_cls(query_dim=dim, heads=n_heads, dim_head=d_head, dropout=dropout,
|
||||
context_dim=context_dim if self.disable_self_attn else None)
|
||||
self.ff = FeedForward(dim, dropout=dropout, glu=gated_ff)
|
||||
self.attn2 = attn_cls(query_dim=dim, context_dim=context_dim, heads=n_heads, dim_head=d_head, dropout=dropout, video_length=video_length, image_cross_attention=image_cross_attention, image_cross_attention_scale=image_cross_attention_scale, image_cross_attention_scale_learnable=image_cross_attention_scale_learnable,text_context_len=text_context_len)
|
||||
self.image_cross_attention = image_cross_attention
|
||||
|
||||
self.norm1 = nn.LayerNorm(dim)
|
||||
self.norm2 = nn.LayerNorm(dim)
|
||||
self.norm3 = nn.LayerNorm(dim)
|
||||
self.checkpoint = checkpoint
|
||||
|
||||
|
||||
def forward(self, x, context=None, mask=None, **kwargs):
|
||||
## implementation tricks: because checkpointing doesn't support non-tensor (e.g. None or scalar) arguments
|
||||
input_tuple = (x,) ## should not be (x), otherwise *input_tuple will decouple x into multiple arguments
|
||||
if context is not None:
|
||||
input_tuple = (x, context)
|
||||
if mask is not None:
|
||||
forward_mask = partial(self._forward, mask=mask)
|
||||
return checkpoint(forward_mask, (x,), self.parameters(), self.checkpoint)
|
||||
return checkpoint(self._forward, input_tuple, self.parameters(), self.checkpoint)
|
||||
|
||||
|
||||
def _forward(self, x, context=None, mask=None):
|
||||
x = self.attn1(self.norm1(x), context=context if self.disable_self_attn else None, mask=mask) + x
|
||||
x = self.attn2(self.norm2(x), context=context, mask=mask) + x
|
||||
x = self.ff(self.norm3(x)) + x
|
||||
return x
|
||||
|
||||
|
||||
class SpatialTransformer(nn.Module):
|
||||
"""
|
||||
Transformer block for image-like data in spatial axis.
|
||||
First, project the input (aka embedding)
|
||||
and reshape to b, t, d.
|
||||
Then apply standard transformer action.
|
||||
Finally, reshape to image
|
||||
NEW: use_linear for more efficiency instead of the 1x1 convs
|
||||
"""
|
||||
|
||||
def __init__(self, in_channels, n_heads, d_head, depth=1, dropout=0., context_dim=None,
|
||||
use_checkpoint=True, disable_self_attn=False, use_linear=False, video_length=None,
|
||||
image_cross_attention=False, image_cross_attention_scale_learnable=False):
|
||||
super().__init__()
|
||||
self.in_channels = in_channels
|
||||
inner_dim = n_heads * d_head
|
||||
self.norm = torch.nn.GroupNorm(num_groups=32, num_channels=in_channels, eps=1e-6, affine=True)
|
||||
if not use_linear:
|
||||
self.proj_in = Conv2d(in_channels, inner_dim, kernel_size=1, stride=1, padding=0)
|
||||
else:
|
||||
self.proj_in = Linear(in_channels, inner_dim)
|
||||
|
||||
attention_cls = None
|
||||
self.transformer_blocks = nn.ModuleList([
|
||||
BasicTransformerBlock(
|
||||
inner_dim,
|
||||
n_heads,
|
||||
d_head,
|
||||
dropout=dropout,
|
||||
context_dim=context_dim,
|
||||
disable_self_attn=disable_self_attn,
|
||||
checkpoint=use_checkpoint,
|
||||
attention_cls=attention_cls,
|
||||
video_length=video_length,
|
||||
image_cross_attention=image_cross_attention,
|
||||
image_cross_attention_scale_learnable=image_cross_attention_scale_learnable,
|
||||
) for d in range(depth)
|
||||
])
|
||||
if not use_linear:
|
||||
self.proj_out = zero_module(Conv2d(inner_dim, in_channels, kernel_size=1, stride=1, padding=0))
|
||||
else:
|
||||
self.proj_out = zero_module(Linear(inner_dim, in_channels))
|
||||
self.use_linear = use_linear
|
||||
|
||||
|
||||
def forward(self, x, context=None, **kwargs):
|
||||
b, c, h, w = x.shape
|
||||
x_in = x
|
||||
x = self.norm(x)
|
||||
if not self.use_linear:
|
||||
x = self.proj_in(x)
|
||||
x = rearrange(x, 'b c h w -> b (h w) c').contiguous()
|
||||
if self.use_linear:
|
||||
x = self.proj_in(x)
|
||||
for i, block in enumerate(self.transformer_blocks):
|
||||
x = block(x, context=context, **kwargs)
|
||||
if self.use_linear:
|
||||
x = self.proj_out(x)
|
||||
x = rearrange(x, 'b (h w) c -> b c h w', h=h, w=w).contiguous()
|
||||
if not self.use_linear:
|
||||
x = self.proj_out(x)
|
||||
return x + x_in
|
||||
|
||||
|
||||
class TemporalTransformer(nn.Module):
|
||||
"""
|
||||
Transformer block for image-like data in temporal axis.
|
||||
First, reshape to b, t, d.
|
||||
Then apply standard transformer action.
|
||||
Finally, reshape to image
|
||||
"""
|
||||
def __init__(self, in_channels, n_heads, d_head, depth=1, dropout=0., context_dim=None,
|
||||
use_checkpoint=True, use_linear=False, only_self_att=True, causal_attention=False, causal_block_size=1,
|
||||
relative_position=False, temporal_length=None):
|
||||
super().__init__()
|
||||
self.only_self_att = only_self_att
|
||||
self.relative_position = relative_position
|
||||
self.causal_attention = causal_attention
|
||||
self.causal_block_size = causal_block_size
|
||||
|
||||
self.in_channels = in_channels
|
||||
inner_dim = n_heads * d_head
|
||||
self.norm = torch.nn.GroupNorm(num_groups=32, num_channels=in_channels, eps=1e-6, affine=True)
|
||||
self.proj_in = nn.Conv1d(in_channels, inner_dim, kernel_size=1, stride=1, padding=0)
|
||||
if not use_linear:
|
||||
self.proj_in = nn.Conv1d(in_channels, inner_dim, kernel_size=1, stride=1, padding=0)
|
||||
else:
|
||||
self.proj_in = Linear(in_channels, inner_dim)
|
||||
|
||||
if relative_position:
|
||||
assert(temporal_length is not None)
|
||||
attention_cls = partial(CrossAttention, relative_position=True, temporal_length=temporal_length)
|
||||
else:
|
||||
attention_cls = partial(CrossAttention, temporal_length=temporal_length)
|
||||
if self.causal_attention:
|
||||
assert(temporal_length is not None)
|
||||
self.mask = torch.tril(torch.ones([1, temporal_length, temporal_length]))
|
||||
|
||||
if self.only_self_att:
|
||||
context_dim = None
|
||||
self.transformer_blocks = nn.ModuleList([
|
||||
BasicTransformerBlock(
|
||||
inner_dim,
|
||||
n_heads,
|
||||
d_head,
|
||||
dropout=dropout,
|
||||
context_dim=context_dim,
|
||||
attention_cls=attention_cls,
|
||||
checkpoint=use_checkpoint) for d in range(depth)
|
||||
])
|
||||
if not use_linear:
|
||||
self.proj_out = zero_module(nn.Conv1d(inner_dim, in_channels, kernel_size=1, stride=1, padding=0))
|
||||
else:
|
||||
self.proj_out = zero_module(Linear(inner_dim, in_channels))
|
||||
self.use_linear = use_linear
|
||||
|
||||
def forward(self, x, context=None):
|
||||
b, c, t, h, w = x.shape
|
||||
x_in = x
|
||||
x = self.norm(x)
|
||||
x = rearrange(x, 'b c t h w -> (b h w) c t').contiguous()
|
||||
if not self.use_linear:
|
||||
x = self.proj_in(x)
|
||||
x = rearrange(x, 'bhw c t -> bhw t c').contiguous()
|
||||
if self.use_linear:
|
||||
x = self.proj_in(x)
|
||||
|
||||
temp_mask = None
|
||||
if self.causal_attention:
|
||||
# slice the from mask map
|
||||
temp_mask = self.mask[:,:t,:t].to(x.device)
|
||||
|
||||
if temp_mask is not None:
|
||||
mask = temp_mask.to(x.device)
|
||||
mask = repeat(mask, 'l i j -> (l bhw) i j', bhw=b*h*w)
|
||||
else:
|
||||
mask = None
|
||||
|
||||
if self.only_self_att:
|
||||
## note: if no context is given, cross-attention defaults to self-attention
|
||||
for i, block in enumerate(self.transformer_blocks):
|
||||
x = block(x, mask=mask)
|
||||
x = rearrange(x, '(b hw) t c -> b hw t c', b=b).contiguous()
|
||||
else:
|
||||
x = rearrange(x, '(b hw) t c -> b hw t c', b=b).contiguous()
|
||||
context = rearrange(context, '(b t) l con -> b t l con', t=t).contiguous()
|
||||
for i, block in enumerate(self.transformer_blocks):
|
||||
# calculate each batch one by one (since number in shape could not greater then 65,535 for some package)
|
||||
for j in range(b):
|
||||
context_j = repeat(
|
||||
context[j],
|
||||
't l con -> (t r) l con', r=(h * w) // t, t=t).contiguous()
|
||||
## note: causal mask will not applied in cross-attention case
|
||||
x[j] = block(x[j], context=context_j)
|
||||
|
||||
if self.use_linear:
|
||||
x = self.proj_out(x)
|
||||
x = rearrange(x, 'b (h w) t c -> b c t h w', h=h, w=w).contiguous()
|
||||
if not self.use_linear:
|
||||
x = rearrange(x, 'b hw t c -> (b hw) c t').contiguous()
|
||||
x = self.proj_out(x)
|
||||
x = rearrange(x, '(b h w) c t -> b c t h w', b=b, h=h, w=w).contiguous()
|
||||
|
||||
return x + x_in
|
||||
|
||||
|
||||
class GEGLU(nn.Module):
|
||||
def __init__(self, dim_in, dim_out):
|
||||
super().__init__()
|
||||
self.proj = Linear(dim_in, dim_out * 2)
|
||||
|
||||
def forward(self, x):
|
||||
x, gate = self.proj(x).chunk(2, dim=-1)
|
||||
return x * F.gelu(gate)
|
||||
|
||||
|
||||
class FeedForward(nn.Module):
|
||||
def __init__(self, dim, dim_out=None, mult=4, glu=False, dropout=0.):
|
||||
super().__init__()
|
||||
inner_dim = int(dim * mult)
|
||||
dim_out = default(dim_out, dim)
|
||||
project_in = nn.Sequential(
|
||||
Linear(dim, inner_dim),
|
||||
nn.GELU()
|
||||
) if not glu else GEGLU(dim, inner_dim)
|
||||
|
||||
self.net = nn.Sequential(
|
||||
project_in,
|
||||
nn.Dropout(dropout),
|
||||
Linear(inner_dim, dim_out)
|
||||
)
|
||||
|
||||
def forward(self, x):
|
||||
return self.net(x)
|
||||
|
||||
|
||||
class LinearAttention(nn.Module):
|
||||
def __init__(self, dim, heads=4, dim_head=32):
|
||||
super().__init__()
|
||||
self.heads = heads
|
||||
hidden_dim = dim_head * heads
|
||||
self.to_qkv = Conv2d(dim, hidden_dim * 3, 1, bias = False)
|
||||
self.to_out = Conv2d(hidden_dim, dim, 1)
|
||||
|
||||
def forward(self, x):
|
||||
b, c, h, w = x.shape
|
||||
qkv = self.to_qkv(x)
|
||||
q, k, v = rearrange(qkv, 'b (qkv heads c) h w -> qkv b heads c (h w)', heads = self.heads, qkv=3)
|
||||
k = k.softmax(dim=-1)
|
||||
context = torch.einsum('bhdn,bhen->bhde', k, v)
|
||||
out = torch.einsum('bhde,bhdn->bhen', context, q)
|
||||
out = rearrange(out, 'b heads c (h w) -> b (heads c) h w', heads=self.heads, h=h, w=w)
|
||||
return self.to_out(out)
|
||||
|
||||
|
||||
class SpatialSelfAttention(nn.Module):
|
||||
def __init__(self, in_channels):
|
||||
super().__init__()
|
||||
self.in_channels = in_channels
|
||||
|
||||
self.norm = torch.nn.GroupNorm(num_groups=32, num_channels=in_channels, eps=1e-6, affine=True)
|
||||
self.q = torch.Conv2d(in_channels,
|
||||
in_channels,
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0)
|
||||
self.k = torch.Conv2d(in_channels,
|
||||
in_channels,
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0)
|
||||
self.v = torch.Conv2d(in_channels,
|
||||
in_channels,
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0)
|
||||
self.proj_out = torch.Conv2d(in_channels,
|
||||
in_channels,
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0)
|
||||
|
||||
def forward(self, x):
|
||||
h_ = x
|
||||
h_ = self.norm(h_)
|
||||
q = self.q(h_)
|
||||
k = self.k(h_)
|
||||
v = self.v(h_)
|
||||
|
||||
# compute attention
|
||||
b,c,h,w = q.shape
|
||||
q = rearrange(q, 'b c h w -> b (h w) c')
|
||||
k = rearrange(k, 'b c h w -> b c (h w)')
|
||||
w_ = torch.einsum('bij,bjk->bik', q, k)
|
||||
|
||||
w_ = w_ * (int(c)**(-0.5))
|
||||
w_ = torch.nn.functional.softmax(w_, dim=2)
|
||||
|
||||
# attend to values
|
||||
v = rearrange(v, 'b c h w -> b c (h w)')
|
||||
w_ = rearrange(w_, 'b i j -> b j i')
|
||||
h_ = torch.einsum('bij,bjk->bik', v, w_)
|
||||
h_ = rearrange(h_, 'b c (h w) -> b c h w', h=h)
|
||||
h_ = self.proj_out(h_)
|
||||
|
||||
return x+h_
|
||||
@@ -0,0 +1,389 @@
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import kornia
|
||||
import open_clip
|
||||
from torch.utils.checkpoint import checkpoint
|
||||
from transformers import T5Tokenizer, T5EncoderModel, CLIPTokenizer, CLIPTextModel
|
||||
from ....lvdm.common import autocast
|
||||
from ....utils.utils import count_params
|
||||
|
||||
|
||||
class AbstractEncoder(nn.Module):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
|
||||
def encode(self, *args, **kwargs):
|
||||
raise NotImplementedError
|
||||
|
||||
|
||||
class IdentityEncoder(AbstractEncoder):
|
||||
def encode(self, x):
|
||||
return x
|
||||
|
||||
|
||||
class ClassEmbedder(nn.Module):
|
||||
def __init__(self, embed_dim, n_classes=1000, key='class', ucg_rate=0.1):
|
||||
super().__init__()
|
||||
self.key = key
|
||||
self.embedding = nn.Embedding(n_classes, embed_dim)
|
||||
self.n_classes = n_classes
|
||||
self.ucg_rate = ucg_rate
|
||||
|
||||
def forward(self, batch, key=None, disable_dropout=False):
|
||||
if key is None:
|
||||
key = self.key
|
||||
# this is for use in crossattn
|
||||
c = batch[key][:, None]
|
||||
if self.ucg_rate > 0. and not disable_dropout:
|
||||
mask = 1. - torch.bernoulli(torch.ones_like(c) * self.ucg_rate)
|
||||
c = mask * c + (1 - mask) * torch.ones_like(c) * (self.n_classes - 1)
|
||||
c = c.long()
|
||||
c = self.embedding(c)
|
||||
return c
|
||||
|
||||
def get_unconditional_conditioning(self, bs, device="cuda"):
|
||||
uc_class = self.n_classes - 1 # 1000 classes --> 0 ... 999, one extra class for ucg (class 1000)
|
||||
uc = torch.ones((bs,), device=device) * uc_class
|
||||
uc = {self.key: uc}
|
||||
return uc
|
||||
|
||||
|
||||
def disabled_train(self, mode=True):
|
||||
"""Overwrite model.train with this function to make sure train/eval mode
|
||||
does not change anymore."""
|
||||
return self
|
||||
|
||||
|
||||
class FrozenT5Embedder(AbstractEncoder):
|
||||
"""Uses the T5 transformer encoder for text"""
|
||||
|
||||
def __init__(self, version="google/t5-v1_1-large", device="cuda", max_length=77,
|
||||
freeze=True): # others are google/t5-v1_1-xl and google/t5-v1_1-xxl
|
||||
super().__init__()
|
||||
self.tokenizer = T5Tokenizer.from_pretrained(version)
|
||||
self.transformer = T5EncoderModel.from_pretrained(version)
|
||||
self.device = device
|
||||
self.max_length = max_length # TODO: typical value?
|
||||
if freeze:
|
||||
self.freeze()
|
||||
|
||||
def freeze(self):
|
||||
self.transformer = self.transformer.eval()
|
||||
# self.train = disabled_train
|
||||
for param in self.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
def forward(self, text):
|
||||
batch_encoding = self.tokenizer(text, truncation=True, max_length=self.max_length, return_length=True,
|
||||
return_overflowing_tokens=False, padding="max_length", return_tensors="pt")
|
||||
tokens = batch_encoding["input_ids"].to(self.device)
|
||||
outputs = self.transformer(input_ids=tokens)
|
||||
|
||||
z = outputs.last_hidden_state
|
||||
return z
|
||||
|
||||
def encode(self, text):
|
||||
return self(text)
|
||||
|
||||
|
||||
class FrozenCLIPEmbedder(AbstractEncoder):
|
||||
"""Uses the CLIP transformer encoder for text (from huggingface)"""
|
||||
LAYERS = [
|
||||
"last",
|
||||
"pooled",
|
||||
"hidden"
|
||||
]
|
||||
|
||||
def __init__(self, version="openai/clip-vit-large-patch14", device="cuda", max_length=77,
|
||||
freeze=True, layer="last", layer_idx=None): # clip-vit-base-patch32
|
||||
super().__init__()
|
||||
assert layer in self.LAYERS
|
||||
self.tokenizer = CLIPTokenizer.from_pretrained(version)
|
||||
self.transformer = CLIPTextModel.from_pretrained(version)
|
||||
self.device = device
|
||||
self.max_length = max_length
|
||||
if freeze:
|
||||
self.freeze()
|
||||
self.layer = layer
|
||||
self.layer_idx = layer_idx
|
||||
if layer == "hidden":
|
||||
assert layer_idx is not None
|
||||
assert 0 <= abs(layer_idx) <= 12
|
||||
|
||||
def freeze(self):
|
||||
self.transformer = self.transformer.eval()
|
||||
# self.train = disabled_train
|
||||
for param in self.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
def forward(self, text):
|
||||
batch_encoding = self.tokenizer(text, truncation=True, max_length=self.max_length, return_length=True,
|
||||
return_overflowing_tokens=False, padding="max_length", return_tensors="pt")
|
||||
tokens = batch_encoding["input_ids"].to(self.device)
|
||||
outputs = self.transformer(input_ids=tokens, output_hidden_states=self.layer == "hidden")
|
||||
if self.layer == "last":
|
||||
z = outputs.last_hidden_state
|
||||
elif self.layer == "pooled":
|
||||
z = outputs.pooler_output[:, None, :]
|
||||
else:
|
||||
z = outputs.hidden_states[self.layer_idx]
|
||||
return z
|
||||
|
||||
def encode(self, text):
|
||||
return self(text)
|
||||
|
||||
|
||||
class ClipImageEmbedder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
model,
|
||||
jit=False,
|
||||
device='cuda' if torch.cuda.is_available() else 'cpu',
|
||||
antialias=True,
|
||||
ucg_rate=0.
|
||||
):
|
||||
super().__init__()
|
||||
from clip import load as load_clip
|
||||
self.model, _ = load_clip(name=model, device=device, jit=jit)
|
||||
|
||||
self.antialias = antialias
|
||||
|
||||
self.register_buffer('mean', torch.Tensor([0.48145466, 0.4578275, 0.40821073]), persistent=False)
|
||||
self.register_buffer('std', torch.Tensor([0.26862954, 0.26130258, 0.27577711]), persistent=False)
|
||||
self.ucg_rate = ucg_rate
|
||||
|
||||
def preprocess(self, x):
|
||||
# normalize to [0,1]
|
||||
x = kornia.geometry.resize(x, (224, 224),
|
||||
interpolation='bicubic', align_corners=True,
|
||||
antialias=self.antialias)
|
||||
x = (x + 1.) / 2.
|
||||
# re-normalize according to clip
|
||||
x = kornia.enhance.normalize(x, self.mean, self.std)
|
||||
return x
|
||||
|
||||
def forward(self, x, no_dropout=False):
|
||||
# x is assumed to be in range [-1,1]
|
||||
out = self.model.encode_image(self.preprocess(x))
|
||||
out = out.to(x.dtype)
|
||||
if self.ucg_rate > 0. and not no_dropout:
|
||||
out = torch.bernoulli((1. - self.ucg_rate) * torch.ones(out.shape[0], device=out.device))[:, None] * out
|
||||
return out
|
||||
|
||||
|
||||
class FrozenOpenCLIPEmbedder(AbstractEncoder):
|
||||
"""
|
||||
Uses the OpenCLIP transformer encoder for text
|
||||
"""
|
||||
LAYERS = [
|
||||
# "pooled",
|
||||
"last",
|
||||
"penultimate"
|
||||
]
|
||||
|
||||
def __init__(self, arch="ViT-H-14", version="laion2b_s32b_b79k", device="cuda", max_length=77,
|
||||
freeze=True, layer="last"):
|
||||
super().__init__()
|
||||
assert layer in self.LAYERS
|
||||
model, _, _ = open_clip.create_model_and_transforms(arch, device=torch.device('cpu'), pretrained=version)
|
||||
del model.visual
|
||||
self.model = model
|
||||
|
||||
self.device = device
|
||||
self.max_length = max_length
|
||||
if freeze:
|
||||
self.freeze()
|
||||
self.layer = layer
|
||||
if self.layer == "last":
|
||||
self.layer_idx = 0
|
||||
elif self.layer == "penultimate":
|
||||
self.layer_idx = 1
|
||||
else:
|
||||
raise NotImplementedError()
|
||||
|
||||
def freeze(self):
|
||||
self.model = self.model.eval()
|
||||
for param in self.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
def forward(self, text):
|
||||
tokens = open_clip.tokenize(text) ## all clip models use 77 as context length
|
||||
z = self.encode_with_transformer(tokens.to(self.device))
|
||||
return z
|
||||
|
||||
def encode_with_transformer(self, text):
|
||||
x = self.model.token_embedding(text) # [batch_size, n_ctx, d_model]
|
||||
x = x + self.model.positional_embedding
|
||||
x = x.permute(1, 0, 2) # NLD -> LND
|
||||
x = self.text_transformer_forward(x, attn_mask=self.model.attn_mask)
|
||||
x = x.permute(1, 0, 2) # LND -> NLD
|
||||
x = self.model.ln_final(x)
|
||||
return x
|
||||
|
||||
def text_transformer_forward(self, x: torch.Tensor, attn_mask=None):
|
||||
for i, r in enumerate(self.model.transformer.resblocks):
|
||||
if i == len(self.model.transformer.resblocks) - self.layer_idx:
|
||||
break
|
||||
if self.model.transformer.grad_checkpointing and not torch.jit.is_scripting():
|
||||
x = checkpoint(r, x, attn_mask)
|
||||
else:
|
||||
x = r(x, attn_mask=attn_mask)
|
||||
return x
|
||||
|
||||
def encode(self, text):
|
||||
return self(text)
|
||||
|
||||
|
||||
class FrozenOpenCLIPImageEmbedder(AbstractEncoder):
|
||||
"""
|
||||
Uses the OpenCLIP vision transformer encoder for images
|
||||
"""
|
||||
|
||||
def __init__(self, arch="ViT-H-14", version="laion2b_s32b_b79k", device="cuda", max_length=77,
|
||||
freeze=True, layer="pooled", antialias=True, ucg_rate=0.):
|
||||
super().__init__()
|
||||
model, _, _ = open_clip.create_model_and_transforms(arch, device=torch.device('cpu'),
|
||||
pretrained=version, )
|
||||
del model.transformer
|
||||
self.model = model
|
||||
# self.mapper = torch.nn.Linear(1280, 1024)
|
||||
self.device = device
|
||||
self.max_length = max_length
|
||||
if freeze:
|
||||
self.freeze()
|
||||
self.layer = layer
|
||||
if self.layer == "penultimate":
|
||||
raise NotImplementedError()
|
||||
self.layer_idx = 1
|
||||
|
||||
self.antialias = antialias
|
||||
|
||||
self.register_buffer('mean', torch.Tensor([0.48145466, 0.4578275, 0.40821073]), persistent=False)
|
||||
self.register_buffer('std', torch.Tensor([0.26862954, 0.26130258, 0.27577711]), persistent=False)
|
||||
self.ucg_rate = ucg_rate
|
||||
|
||||
def preprocess(self, x):
|
||||
# normalize to [0,1]
|
||||
x = kornia.geometry.resize(x, (224, 224),
|
||||
interpolation='bicubic', align_corners=True,
|
||||
antialias=self.antialias)
|
||||
x = (x + 1.) / 2.
|
||||
# renormalize according to clip
|
||||
x = kornia.enhance.normalize(x, self.mean, self.std)
|
||||
return x
|
||||
|
||||
def freeze(self):
|
||||
self.model = self.model.eval()
|
||||
for param in self.model.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
@autocast
|
||||
def forward(self, image, no_dropout=False):
|
||||
z = self.encode_with_vision_transformer(image)
|
||||
if self.ucg_rate > 0. and not no_dropout:
|
||||
z = torch.bernoulli((1. - self.ucg_rate) * torch.ones(z.shape[0], device=z.device))[:, None] * z
|
||||
return z
|
||||
|
||||
def encode_with_vision_transformer(self, img):
|
||||
img = self.preprocess(img)
|
||||
x = self.model.visual(img)
|
||||
return x
|
||||
|
||||
def encode(self, text):
|
||||
return self(text)
|
||||
|
||||
class FrozenOpenCLIPImageEmbedderV2(AbstractEncoder):
|
||||
"""
|
||||
Uses the OpenCLIP vision transformer encoder for images
|
||||
"""
|
||||
|
||||
def __init__(self, arch="ViT-H-14", version="laion2b_s32b_b79k", device="cuda",
|
||||
freeze=True, layer="pooled", antialias=True):
|
||||
super().__init__()
|
||||
model, _, _ = open_clip.create_model_and_transforms(arch, device=torch.device('cpu'),
|
||||
pretrained=version, )
|
||||
del model.transformer
|
||||
self.model = model
|
||||
self.device = device
|
||||
|
||||
if freeze:
|
||||
self.freeze()
|
||||
self.layer = layer
|
||||
if self.layer == "penultimate":
|
||||
raise NotImplementedError()
|
||||
self.layer_idx = 1
|
||||
|
||||
self.antialias = antialias
|
||||
|
||||
self.register_buffer('mean', torch.Tensor([0.48145466, 0.4578275, 0.40821073]), persistent=False)
|
||||
self.register_buffer('std', torch.Tensor([0.26862954, 0.26130258, 0.27577711]), persistent=False)
|
||||
|
||||
|
||||
def preprocess(self, x):
|
||||
# normalize to [0,1]
|
||||
x = kornia.geometry.resize(x, (224, 224),
|
||||
interpolation='bicubic', align_corners=True,
|
||||
antialias=self.antialias)
|
||||
x = (x + 1.) / 2.
|
||||
# renormalize according to clip
|
||||
x = kornia.enhance.normalize(x, self.mean, self.std)
|
||||
return x
|
||||
|
||||
def freeze(self):
|
||||
self.model = self.model.eval()
|
||||
for param in self.model.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
def forward(self, image, no_dropout=False):
|
||||
## image: b c h w
|
||||
z = self.encode_with_vision_transformer(image)
|
||||
return z
|
||||
|
||||
def encode_with_vision_transformer(self, x):
|
||||
x = self.preprocess(x)
|
||||
|
||||
# to patches - whether to use dual patchnorm - https://arxiv.org/abs/2302.01327v1
|
||||
if self.model.visual.input_patchnorm:
|
||||
# einops - rearrange(x, 'b c (h p1) (w p2) -> b (h w) (c p1 p2)')
|
||||
x = x.reshape(x.shape[0], x.shape[1], self.model.visual.grid_size[0], self.model.visual.patch_size[0], self.model.visual.grid_size[1], self.model.visual.patch_size[1])
|
||||
x = x.permute(0, 2, 4, 1, 3, 5)
|
||||
x = x.reshape(x.shape[0], self.model.visual.grid_size[0] * self.model.visual.grid_size[1], -1)
|
||||
x = self.model.visual.patchnorm_pre_ln(x)
|
||||
x = self.model.visual.conv1(x)
|
||||
else:
|
||||
x = self.model.visual.conv1(x) # shape = [*, width, grid, grid]
|
||||
x = x.reshape(x.shape[0], x.shape[1], -1) # shape = [*, width, grid ** 2]
|
||||
x = x.permute(0, 2, 1) # shape = [*, grid ** 2, width]
|
||||
|
||||
# class embeddings and positional embeddings
|
||||
x = torch.cat(
|
||||
[self.model.visual.class_embedding.to(x.dtype) + torch.zeros(x.shape[0], 1, x.shape[-1], dtype=x.dtype, device=x.device),
|
||||
x], dim=1) # shape = [*, grid ** 2 + 1, width]
|
||||
x = x + self.model.visual.positional_embedding.to(x.dtype)
|
||||
|
||||
# a patch_dropout of 0. would mean it is disabled and this function would do nothing but return what was passed in
|
||||
x = self.model.visual.patch_dropout(x)
|
||||
x = self.model.visual.ln_pre(x)
|
||||
|
||||
x = x.permute(1, 0, 2) # NLD -> LND
|
||||
x = self.model.visual.transformer(x)
|
||||
x = x.permute(1, 0, 2) # LND -> NLD
|
||||
|
||||
return x
|
||||
|
||||
class FrozenCLIPT5Encoder(AbstractEncoder):
|
||||
def __init__(self, clip_version="openai/clip-vit-large-patch14", t5_version="google/t5-v1_1-xl", device="cuda",
|
||||
clip_max_length=77, t5_max_length=77):
|
||||
super().__init__()
|
||||
self.clip_encoder = FrozenCLIPEmbedder(clip_version, device, max_length=clip_max_length)
|
||||
self.t5_encoder = FrozenT5Embedder(t5_version, device, max_length=t5_max_length)
|
||||
print(f"{self.clip_encoder.__class__.__name__} has {count_params(self.clip_encoder) * 1.e-6:.2f} M parameters, "
|
||||
f"{self.t5_encoder.__class__.__name__} comes with {count_params(self.t5_encoder) * 1.e-6:.2f} M params.")
|
||||
|
||||
def encode(self, text):
|
||||
return self(text)
|
||||
|
||||
def forward(self, text):
|
||||
clip_z = self.clip_encoder.encode(text)
|
||||
t5_z = self.t5_encoder.encode(text)
|
||||
return [clip_z, t5_z]
|
||||
@@ -0,0 +1,145 @@
|
||||
# modified from https://github.com/mlfoundations/open_flamingo/blob/main/open_flamingo/src/helpers.py
|
||||
# and https://github.com/lucidrains/imagen-pytorch/blob/main/imagen_pytorch/imagen_pytorch.py
|
||||
# and https://github.com/tencent-ailab/IP-Adapter/blob/main/ip_adapter/resampler.py
|
||||
import math
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
|
||||
|
||||
class ImageProjModel(nn.Module):
|
||||
"""Projection Model"""
|
||||
def __init__(self, cross_attention_dim=1024, clip_embeddings_dim=1024, clip_extra_context_tokens=4):
|
||||
super().__init__()
|
||||
self.cross_attention_dim = cross_attention_dim
|
||||
self.clip_extra_context_tokens = clip_extra_context_tokens
|
||||
self.proj = nn.Linear(clip_embeddings_dim, self.clip_extra_context_tokens * cross_attention_dim)
|
||||
self.norm = nn.LayerNorm(cross_attention_dim)
|
||||
|
||||
def forward(self, image_embeds):
|
||||
#embeds = image_embeds
|
||||
embeds = image_embeds.type(list(self.proj.parameters())[0].dtype)
|
||||
clip_extra_context_tokens = self.proj(embeds).reshape(-1, self.clip_extra_context_tokens, self.cross_attention_dim)
|
||||
clip_extra_context_tokens = self.norm(clip_extra_context_tokens)
|
||||
return clip_extra_context_tokens
|
||||
|
||||
|
||||
# FFN
|
||||
def FeedForward(dim, mult=4):
|
||||
inner_dim = int(dim * mult)
|
||||
return nn.Sequential(
|
||||
nn.LayerNorm(dim),
|
||||
nn.Linear(dim, inner_dim, bias=False),
|
||||
nn.GELU(),
|
||||
nn.Linear(inner_dim, dim, bias=False),
|
||||
)
|
||||
|
||||
|
||||
def reshape_tensor(x, heads):
|
||||
bs, length, width = x.shape
|
||||
#(bs, length, width) --> (bs, length, n_heads, dim_per_head)
|
||||
x = x.view(bs, length, heads, -1)
|
||||
# (bs, length, n_heads, dim_per_head) --> (bs, n_heads, length, dim_per_head)
|
||||
x = x.transpose(1, 2)
|
||||
# (bs, n_heads, length, dim_per_head) --> (bs*n_heads, length, dim_per_head)
|
||||
x = x.reshape(bs, heads, length, -1)
|
||||
return x
|
||||
|
||||
|
||||
class PerceiverAttention(nn.Module):
|
||||
def __init__(self, *, dim, dim_head=64, heads=8):
|
||||
super().__init__()
|
||||
self.scale = dim_head**-0.5
|
||||
self.dim_head = dim_head
|
||||
self.heads = heads
|
||||
inner_dim = dim_head * heads
|
||||
|
||||
self.norm1 = nn.LayerNorm(dim)
|
||||
self.norm2 = nn.LayerNorm(dim)
|
||||
|
||||
self.to_q = nn.Linear(dim, inner_dim, bias=False)
|
||||
self.to_kv = nn.Linear(dim, inner_dim * 2, bias=False)
|
||||
self.to_out = nn.Linear(inner_dim, dim, bias=False)
|
||||
|
||||
|
||||
def forward(self, x, latents):
|
||||
"""
|
||||
Args:
|
||||
x (torch.Tensor): image features
|
||||
shape (b, n1, D)
|
||||
latent (torch.Tensor): latent features
|
||||
shape (b, n2, D)
|
||||
"""
|
||||
x = self.norm1(x)
|
||||
latents = self.norm2(latents)
|
||||
|
||||
b, l, _ = latents.shape
|
||||
|
||||
q = self.to_q(latents)
|
||||
kv_input = torch.cat((x, latents), dim=-2)
|
||||
k, v = self.to_kv(kv_input).chunk(2, dim=-1)
|
||||
|
||||
q = reshape_tensor(q, self.heads)
|
||||
k = reshape_tensor(k, self.heads)
|
||||
v = reshape_tensor(v, self.heads)
|
||||
|
||||
# attention
|
||||
scale = 1 / math.sqrt(math.sqrt(self.dim_head))
|
||||
weight = (q * scale) @ (k * scale).transpose(-2, -1) # More stable with f16 than dividing afterwards
|
||||
weight = torch.softmax(weight.float(), dim=-1).type(weight.dtype)
|
||||
out = weight @ v
|
||||
|
||||
out = out.permute(0, 2, 1, 3).reshape(b, l, -1)
|
||||
|
||||
return self.to_out(out)
|
||||
|
||||
|
||||
class Resampler(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
dim=1024,
|
||||
depth=8,
|
||||
dim_head=64,
|
||||
heads=16,
|
||||
num_queries=8,
|
||||
embedding_dim=768,
|
||||
output_dim=1024,
|
||||
ff_mult=4,
|
||||
video_length=None, # using frame-wise version or not
|
||||
):
|
||||
super().__init__()
|
||||
## queries for a single frame / image
|
||||
self.num_queries = num_queries
|
||||
self.video_length = video_length
|
||||
|
||||
## <num_queries> queries for each frame
|
||||
if video_length is not None:
|
||||
num_queries = num_queries * video_length
|
||||
|
||||
self.latents = nn.Parameter(torch.randn(1, num_queries, dim) / dim**0.5)
|
||||
self.proj_in = nn.Linear(embedding_dim, dim)
|
||||
self.proj_out = nn.Linear(dim, output_dim)
|
||||
self.norm_out = nn.LayerNorm(output_dim)
|
||||
|
||||
self.layers = nn.ModuleList([])
|
||||
for _ in range(depth):
|
||||
self.layers.append(
|
||||
nn.ModuleList(
|
||||
[
|
||||
PerceiverAttention(dim=dim, dim_head=dim_head, heads=heads),
|
||||
FeedForward(dim=dim, mult=ff_mult),
|
||||
]
|
||||
)
|
||||
)
|
||||
|
||||
def forward(self, x):
|
||||
latents = self.latents.repeat(x.size(0), 1, 1) ## B (T L) C
|
||||
x = self.proj_in(x)
|
||||
|
||||
for attn, ff in self.layers:
|
||||
latents = attn(x, latents) + latents
|
||||
latents = ff(latents) + latents
|
||||
|
||||
latents = self.proj_out(latents)
|
||||
latents = self.norm_out(latents) # B L C or B (T L) C
|
||||
|
||||
return latents
|
||||
@@ -0,0 +1,844 @@
|
||||
# pytorch_diffusion + derived encoder decoder
|
||||
import math
|
||||
import torch
|
||||
import numpy as np
|
||||
import torch.nn as nn
|
||||
from einops import rearrange
|
||||
from ....utils.utils import instantiate_from_config
|
||||
from ....lvdm.modules.attention import LinearAttention
|
||||
|
||||
def nonlinearity(x):
|
||||
# swish
|
||||
return x*torch.sigmoid(x)
|
||||
|
||||
|
||||
def Normalize(in_channels, num_groups=32):
|
||||
return torch.nn.GroupNorm(num_groups=num_groups, num_channels=in_channels, eps=1e-6, affine=True)
|
||||
|
||||
|
||||
|
||||
class LinAttnBlock(LinearAttention):
|
||||
"""to match AttnBlock usage"""
|
||||
def __init__(self, in_channels):
|
||||
super().__init__(dim=in_channels, heads=1, dim_head=in_channels)
|
||||
|
||||
|
||||
class AttnBlock(nn.Module):
|
||||
def __init__(self, in_channels):
|
||||
super().__init__()
|
||||
self.in_channels = in_channels
|
||||
|
||||
self.norm = Normalize(in_channels)
|
||||
self.q = torch.nn.Conv2d(in_channels,
|
||||
in_channels,
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0)
|
||||
self.k = torch.nn.Conv2d(in_channels,
|
||||
in_channels,
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0)
|
||||
self.v = torch.nn.Conv2d(in_channels,
|
||||
in_channels,
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0)
|
||||
self.proj_out = torch.nn.Conv2d(in_channels,
|
||||
in_channels,
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0)
|
||||
|
||||
def forward(self, x):
|
||||
h_ = x
|
||||
h_ = self.norm(h_)
|
||||
q = self.q(h_)
|
||||
k = self.k(h_)
|
||||
v = self.v(h_)
|
||||
|
||||
# compute attention
|
||||
b,c,h,w = q.shape
|
||||
q = q.reshape(b,c,h*w) # bcl
|
||||
q = q.permute(0,2,1) # bcl -> blc l=hw
|
||||
k = k.reshape(b,c,h*w) # bcl
|
||||
|
||||
w_ = torch.bmm(q,k) # b,hw,hw w[b,i,j]=sum_c q[b,i,c]k[b,c,j]
|
||||
w_ = w_ * (int(c)**(-0.5))
|
||||
w_ = torch.nn.functional.softmax(w_, dim=2)
|
||||
|
||||
# attend to values
|
||||
v = v.reshape(b,c,h*w)
|
||||
w_ = w_.permute(0,2,1) # b,hw,hw (first hw of k, second of q)
|
||||
h_ = torch.bmm(v,w_) # b, c,hw (hw of q) h_[b,c,j] = sum_i v[b,c,i] w_[b,i,j]
|
||||
h_ = h_.reshape(b,c,h,w)
|
||||
|
||||
h_ = self.proj_out(h_)
|
||||
|
||||
return x+h_
|
||||
|
||||
def make_attn(in_channels, attn_type="vanilla"):
|
||||
assert attn_type in ["vanilla", "linear", "none"], f'attn_type {attn_type} unknown'
|
||||
#print(f"making attention of type '{attn_type}' with {in_channels} in_channels")
|
||||
if attn_type == "vanilla":
|
||||
return AttnBlock(in_channels)
|
||||
elif attn_type == "none":
|
||||
return nn.Identity(in_channels)
|
||||
else:
|
||||
return LinAttnBlock(in_channels)
|
||||
|
||||
class Downsample(nn.Module):
|
||||
def __init__(self, in_channels, with_conv):
|
||||
super().__init__()
|
||||
self.with_conv = with_conv
|
||||
self.in_channels = in_channels
|
||||
if self.with_conv:
|
||||
# no asymmetric padding in torch conv, must do it ourselves
|
||||
self.conv = torch.nn.Conv2d(in_channels,
|
||||
in_channels,
|
||||
kernel_size=3,
|
||||
stride=2,
|
||||
padding=0)
|
||||
def forward(self, x):
|
||||
if self.with_conv:
|
||||
pad = (0,1,0,1)
|
||||
x = torch.nn.functional.pad(x, pad, mode="constant", value=0)
|
||||
x = self.conv(x)
|
||||
else:
|
||||
x = torch.nn.functional.avg_pool2d(x, kernel_size=2, stride=2)
|
||||
return x
|
||||
|
||||
class Upsample(nn.Module):
|
||||
def __init__(self, in_channels, with_conv):
|
||||
super().__init__()
|
||||
self.with_conv = with_conv
|
||||
self.in_channels = in_channels
|
||||
if self.with_conv:
|
||||
self.conv = torch.nn.Conv2d(in_channels,
|
||||
in_channels,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1)
|
||||
|
||||
def forward(self, x):
|
||||
x = torch.nn.functional.interpolate(x, scale_factor=2.0, mode="nearest")
|
||||
if self.with_conv:
|
||||
x = self.conv(x)
|
||||
return x
|
||||
|
||||
def get_timestep_embedding(timesteps, embedding_dim):
|
||||
"""
|
||||
This matches the implementation in Denoising Diffusion Probabilistic Models:
|
||||
From Fairseq.
|
||||
Build sinusoidal embeddings.
|
||||
This matches the implementation in tensor2tensor, but differs slightly
|
||||
from the description in Section 3.5 of "Attention Is All You Need".
|
||||
"""
|
||||
assert len(timesteps.shape) == 1
|
||||
|
||||
half_dim = embedding_dim // 2
|
||||
emb = math.log(10000) / (half_dim - 1)
|
||||
emb = torch.exp(torch.arange(half_dim, dtype=torch.float32) * -emb)
|
||||
emb = emb.to(device=timesteps.device)
|
||||
emb = timesteps.float()[:, None] * emb[None, :]
|
||||
emb = torch.cat([torch.sin(emb), torch.cos(emb)], dim=1)
|
||||
if embedding_dim % 2 == 1: # zero pad
|
||||
emb = torch.nn.functional.pad(emb, (0,1,0,0))
|
||||
return emb
|
||||
|
||||
|
||||
|
||||
class ResnetBlock(nn.Module):
|
||||
def __init__(self, *, in_channels, out_channels=None, conv_shortcut=False,
|
||||
dropout, temb_channels=512):
|
||||
super().__init__()
|
||||
self.in_channels = in_channels
|
||||
out_channels = in_channels if out_channels is None else out_channels
|
||||
self.out_channels = out_channels
|
||||
self.use_conv_shortcut = conv_shortcut
|
||||
|
||||
self.norm1 = Normalize(in_channels)
|
||||
self.conv1 = torch.nn.Conv2d(in_channels,
|
||||
out_channels,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1)
|
||||
if temb_channels > 0:
|
||||
self.temb_proj = torch.nn.Linear(temb_channels,
|
||||
out_channels)
|
||||
self.norm2 = Normalize(out_channels)
|
||||
self.dropout = torch.nn.Dropout(dropout)
|
||||
self.conv2 = torch.nn.Conv2d(out_channels,
|
||||
out_channels,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1)
|
||||
if self.in_channels != self.out_channels:
|
||||
if self.use_conv_shortcut:
|
||||
self.conv_shortcut = torch.nn.Conv2d(in_channels,
|
||||
out_channels,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1)
|
||||
else:
|
||||
self.nin_shortcut = torch.nn.Conv2d(in_channels,
|
||||
out_channels,
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0)
|
||||
|
||||
def forward(self, x, temb):
|
||||
h = x
|
||||
h = self.norm1(h)
|
||||
h = nonlinearity(h)
|
||||
h = self.conv1(h)
|
||||
|
||||
if temb is not None:
|
||||
h = h + self.temb_proj(nonlinearity(temb))[:,:,None,None]
|
||||
|
||||
h = self.norm2(h)
|
||||
h = nonlinearity(h)
|
||||
h = self.dropout(h)
|
||||
h = self.conv2(h)
|
||||
|
||||
if self.in_channels != self.out_channels:
|
||||
if self.use_conv_shortcut:
|
||||
x = self.conv_shortcut(x)
|
||||
else:
|
||||
x = self.nin_shortcut(x)
|
||||
|
||||
return x+h
|
||||
|
||||
class Model(nn.Module):
|
||||
def __init__(self, *, ch, out_ch, ch_mult=(1,2,4,8), num_res_blocks,
|
||||
attn_resolutions, dropout=0.0, resamp_with_conv=True, in_channels,
|
||||
resolution, use_timestep=True, use_linear_attn=False, attn_type="vanilla"):
|
||||
super().__init__()
|
||||
if use_linear_attn: attn_type = "linear"
|
||||
self.ch = ch
|
||||
self.temb_ch = self.ch*4
|
||||
self.num_resolutions = len(ch_mult)
|
||||
self.num_res_blocks = num_res_blocks
|
||||
self.resolution = resolution
|
||||
self.in_channels = in_channels
|
||||
|
||||
self.use_timestep = use_timestep
|
||||
if self.use_timestep:
|
||||
# timestep embedding
|
||||
self.temb = nn.Module()
|
||||
self.temb.dense = nn.ModuleList([
|
||||
torch.nn.Linear(self.ch,
|
||||
self.temb_ch),
|
||||
torch.nn.Linear(self.temb_ch,
|
||||
self.temb_ch),
|
||||
])
|
||||
|
||||
# downsampling
|
||||
self.conv_in = torch.nn.Conv2d(in_channels,
|
||||
self.ch,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1)
|
||||
|
||||
curr_res = resolution
|
||||
in_ch_mult = (1,)+tuple(ch_mult)
|
||||
self.down = nn.ModuleList()
|
||||
for i_level in range(self.num_resolutions):
|
||||
block = nn.ModuleList()
|
||||
attn = nn.ModuleList()
|
||||
block_in = ch*in_ch_mult[i_level]
|
||||
block_out = ch*ch_mult[i_level]
|
||||
for i_block in range(self.num_res_blocks):
|
||||
block.append(ResnetBlock(in_channels=block_in,
|
||||
out_channels=block_out,
|
||||
temb_channels=self.temb_ch,
|
||||
dropout=dropout))
|
||||
block_in = block_out
|
||||
if curr_res in attn_resolutions:
|
||||
attn.append(make_attn(block_in, attn_type=attn_type))
|
||||
down = nn.Module()
|
||||
down.block = block
|
||||
down.attn = attn
|
||||
if i_level != self.num_resolutions-1:
|
||||
down.downsample = Downsample(block_in, resamp_with_conv)
|
||||
curr_res = curr_res // 2
|
||||
self.down.append(down)
|
||||
|
||||
# middle
|
||||
self.mid = nn.Module()
|
||||
self.mid.block_1 = ResnetBlock(in_channels=block_in,
|
||||
out_channels=block_in,
|
||||
temb_channels=self.temb_ch,
|
||||
dropout=dropout)
|
||||
self.mid.attn_1 = make_attn(block_in, attn_type=attn_type)
|
||||
self.mid.block_2 = ResnetBlock(in_channels=block_in,
|
||||
out_channels=block_in,
|
||||
temb_channels=self.temb_ch,
|
||||
dropout=dropout)
|
||||
|
||||
# upsampling
|
||||
self.up = nn.ModuleList()
|
||||
for i_level in reversed(range(self.num_resolutions)):
|
||||
block = nn.ModuleList()
|
||||
attn = nn.ModuleList()
|
||||
block_out = ch*ch_mult[i_level]
|
||||
skip_in = ch*ch_mult[i_level]
|
||||
for i_block in range(self.num_res_blocks+1):
|
||||
if i_block == self.num_res_blocks:
|
||||
skip_in = ch*in_ch_mult[i_level]
|
||||
block.append(ResnetBlock(in_channels=block_in+skip_in,
|
||||
out_channels=block_out,
|
||||
temb_channels=self.temb_ch,
|
||||
dropout=dropout))
|
||||
block_in = block_out
|
||||
if curr_res in attn_resolutions:
|
||||
attn.append(make_attn(block_in, attn_type=attn_type))
|
||||
up = nn.Module()
|
||||
up.block = block
|
||||
up.attn = attn
|
||||
if i_level != 0:
|
||||
up.upsample = Upsample(block_in, resamp_with_conv)
|
||||
curr_res = curr_res * 2
|
||||
self.up.insert(0, up) # prepend to get consistent order
|
||||
|
||||
# end
|
||||
self.norm_out = Normalize(block_in)
|
||||
self.conv_out = torch.nn.Conv2d(block_in,
|
||||
out_ch,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1)
|
||||
|
||||
def forward(self, x, t=None, context=None):
|
||||
#assert x.shape[2] == x.shape[3] == self.resolution
|
||||
if context is not None:
|
||||
# assume aligned context, cat along channel axis
|
||||
x = torch.cat((x, context), dim=1)
|
||||
if self.use_timestep:
|
||||
# timestep embedding
|
||||
assert t is not None
|
||||
temb = get_timestep_embedding(t, self.ch)
|
||||
temb = self.temb.dense[0](temb)
|
||||
temb = nonlinearity(temb)
|
||||
temb = self.temb.dense[1](temb)
|
||||
else:
|
||||
temb = None
|
||||
|
||||
# downsampling
|
||||
hs = [self.conv_in(x)]
|
||||
for i_level in range(self.num_resolutions):
|
||||
for i_block in range(self.num_res_blocks):
|
||||
h = self.down[i_level].block[i_block](hs[-1], temb)
|
||||
if len(self.down[i_level].attn) > 0:
|
||||
h = self.down[i_level].attn[i_block](h)
|
||||
hs.append(h)
|
||||
if i_level != self.num_resolutions-1:
|
||||
hs.append(self.down[i_level].downsample(hs[-1]))
|
||||
|
||||
# middle
|
||||
h = hs[-1]
|
||||
h = self.mid.block_1(h, temb)
|
||||
h = self.mid.attn_1(h)
|
||||
h = self.mid.block_2(h, temb)
|
||||
|
||||
# upsampling
|
||||
for i_level in reversed(range(self.num_resolutions)):
|
||||
for i_block in range(self.num_res_blocks+1):
|
||||
h = self.up[i_level].block[i_block](
|
||||
torch.cat([h, hs.pop()], dim=1), temb)
|
||||
if len(self.up[i_level].attn) > 0:
|
||||
h = self.up[i_level].attn[i_block](h)
|
||||
if i_level != 0:
|
||||
h = self.up[i_level].upsample(h)
|
||||
|
||||
# end
|
||||
h = self.norm_out(h)
|
||||
h = nonlinearity(h)
|
||||
h = self.conv_out(h)
|
||||
return h
|
||||
|
||||
def get_last_layer(self):
|
||||
return self.conv_out.weight
|
||||
|
||||
|
||||
class Encoder(nn.Module):
|
||||
def __init__(self, *, ch, out_ch, ch_mult=(1,2,4,8), num_res_blocks,
|
||||
attn_resolutions, dropout=0.0, resamp_with_conv=True, in_channels,
|
||||
resolution, z_channels, double_z=True, use_linear_attn=False, attn_type="vanilla",
|
||||
**ignore_kwargs):
|
||||
super().__init__()
|
||||
if use_linear_attn: attn_type = "linear"
|
||||
self.ch = ch
|
||||
self.temb_ch = 0
|
||||
self.num_resolutions = len(ch_mult)
|
||||
self.num_res_blocks = num_res_blocks
|
||||
self.resolution = resolution
|
||||
self.in_channels = in_channels
|
||||
|
||||
# downsampling
|
||||
self.conv_in = torch.nn.Conv2d(in_channels,
|
||||
self.ch,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1)
|
||||
|
||||
curr_res = resolution
|
||||
in_ch_mult = (1,)+tuple(ch_mult)
|
||||
self.in_ch_mult = in_ch_mult
|
||||
self.down = nn.ModuleList()
|
||||
for i_level in range(self.num_resolutions):
|
||||
block = nn.ModuleList()
|
||||
attn = nn.ModuleList()
|
||||
block_in = ch*in_ch_mult[i_level]
|
||||
block_out = ch*ch_mult[i_level]
|
||||
for i_block in range(self.num_res_blocks):
|
||||
block.append(ResnetBlock(in_channels=block_in,
|
||||
out_channels=block_out,
|
||||
temb_channels=self.temb_ch,
|
||||
dropout=dropout))
|
||||
block_in = block_out
|
||||
if curr_res in attn_resolutions:
|
||||
attn.append(make_attn(block_in, attn_type=attn_type))
|
||||
down = nn.Module()
|
||||
down.block = block
|
||||
down.attn = attn
|
||||
if i_level != self.num_resolutions-1:
|
||||
down.downsample = Downsample(block_in, resamp_with_conv)
|
||||
curr_res = curr_res // 2
|
||||
self.down.append(down)
|
||||
|
||||
# middle
|
||||
self.mid = nn.Module()
|
||||
self.mid.block_1 = ResnetBlock(in_channels=block_in,
|
||||
out_channels=block_in,
|
||||
temb_channels=self.temb_ch,
|
||||
dropout=dropout)
|
||||
self.mid.attn_1 = make_attn(block_in, attn_type=attn_type)
|
||||
self.mid.block_2 = ResnetBlock(in_channels=block_in,
|
||||
out_channels=block_in,
|
||||
temb_channels=self.temb_ch,
|
||||
dropout=dropout)
|
||||
|
||||
# end
|
||||
self.norm_out = Normalize(block_in)
|
||||
self.conv_out = torch.nn.Conv2d(block_in,
|
||||
2*z_channels if double_z else z_channels,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1)
|
||||
|
||||
def forward(self, x):
|
||||
# timestep embedding
|
||||
temb = None
|
||||
|
||||
# print(f'encoder-input={x.shape}')
|
||||
# downsampling
|
||||
hs = [self.conv_in(x)]
|
||||
# print(f'encoder-conv in feat={hs[0].shape}')
|
||||
for i_level in range(self.num_resolutions):
|
||||
for i_block in range(self.num_res_blocks):
|
||||
h = self.down[i_level].block[i_block](hs[-1], temb)
|
||||
# print(f'encoder-down feat={h.shape}')
|
||||
if len(self.down[i_level].attn) > 0:
|
||||
h = self.down[i_level].attn[i_block](h)
|
||||
hs.append(h)
|
||||
if i_level != self.num_resolutions-1:
|
||||
# print(f'encoder-downsample (input)={hs[-1].shape}')
|
||||
hs.append(self.down[i_level].downsample(hs[-1]))
|
||||
# print(f'encoder-downsample (output)={hs[-1].shape}')
|
||||
|
||||
# middle
|
||||
h = hs[-1]
|
||||
h = self.mid.block_1(h, temb)
|
||||
# print(f'encoder-mid1 feat={h.shape}')
|
||||
h = self.mid.attn_1(h)
|
||||
h = self.mid.block_2(h, temb)
|
||||
# print(f'encoder-mid2 feat={h.shape}')
|
||||
|
||||
# end
|
||||
h = self.norm_out(h)
|
||||
h = nonlinearity(h)
|
||||
h = self.conv_out(h)
|
||||
# print(f'end feat={h.shape}')
|
||||
return h
|
||||
|
||||
|
||||
class Decoder(nn.Module):
|
||||
def __init__(self, *, ch, out_ch, ch_mult=(1,2,4,8), num_res_blocks,
|
||||
attn_resolutions, dropout=0.0, resamp_with_conv=True, in_channels,
|
||||
resolution, z_channels, give_pre_end=False, tanh_out=False, use_linear_attn=False,
|
||||
attn_type="vanilla", **ignorekwargs):
|
||||
super().__init__()
|
||||
if use_linear_attn: attn_type = "linear"
|
||||
self.ch = ch
|
||||
self.temb_ch = 0
|
||||
self.num_resolutions = len(ch_mult)
|
||||
self.num_res_blocks = num_res_blocks
|
||||
self.resolution = resolution
|
||||
self.in_channels = in_channels
|
||||
self.give_pre_end = give_pre_end
|
||||
self.tanh_out = tanh_out
|
||||
|
||||
# compute in_ch_mult, block_in and curr_res at lowest res
|
||||
in_ch_mult = (1,)+tuple(ch_mult)
|
||||
block_in = ch*ch_mult[self.num_resolutions-1]
|
||||
curr_res = resolution // 2**(self.num_resolutions-1)
|
||||
self.z_shape = (1,z_channels,curr_res,curr_res)
|
||||
print("AE working on z of shape {} = {} dimensions.".format(
|
||||
self.z_shape, np.prod(self.z_shape)))
|
||||
|
||||
# z to block_in
|
||||
self.conv_in = torch.nn.Conv2d(z_channels,
|
||||
block_in,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1)
|
||||
|
||||
# middle
|
||||
self.mid = nn.Module()
|
||||
self.mid.block_1 = ResnetBlock(in_channels=block_in,
|
||||
out_channels=block_in,
|
||||
temb_channels=self.temb_ch,
|
||||
dropout=dropout)
|
||||
self.mid.attn_1 = make_attn(block_in, attn_type=attn_type)
|
||||
self.mid.block_2 = ResnetBlock(in_channels=block_in,
|
||||
out_channels=block_in,
|
||||
temb_channels=self.temb_ch,
|
||||
dropout=dropout)
|
||||
|
||||
# upsampling
|
||||
self.up = nn.ModuleList()
|
||||
for i_level in reversed(range(self.num_resolutions)):
|
||||
block = nn.ModuleList()
|
||||
attn = nn.ModuleList()
|
||||
block_out = ch*ch_mult[i_level]
|
||||
for i_block in range(self.num_res_blocks+1):
|
||||
block.append(ResnetBlock(in_channels=block_in,
|
||||
out_channels=block_out,
|
||||
temb_channels=self.temb_ch,
|
||||
dropout=dropout))
|
||||
block_in = block_out
|
||||
if curr_res in attn_resolutions:
|
||||
attn.append(make_attn(block_in, attn_type=attn_type))
|
||||
up = nn.Module()
|
||||
up.block = block
|
||||
up.attn = attn
|
||||
if i_level != 0:
|
||||
up.upsample = Upsample(block_in, resamp_with_conv)
|
||||
curr_res = curr_res * 2
|
||||
self.up.insert(0, up) # prepend to get consistent order
|
||||
|
||||
# end
|
||||
self.norm_out = Normalize(block_in)
|
||||
self.conv_out = torch.nn.Conv2d(block_in,
|
||||
out_ch,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1)
|
||||
|
||||
def forward(self, z):
|
||||
#assert z.shape[1:] == self.z_shape[1:]
|
||||
self.last_z_shape = z.shape
|
||||
|
||||
# print(f'decoder-input={z.shape}')
|
||||
# timestep embedding
|
||||
temb = None
|
||||
|
||||
# z to block_in
|
||||
h = self.conv_in(z)
|
||||
# print(f'decoder-conv in feat={h.shape}')
|
||||
|
||||
# middle
|
||||
h = self.mid.block_1(h, temb)
|
||||
h = self.mid.attn_1(h)
|
||||
h = self.mid.block_2(h, temb)
|
||||
# print(f'decoder-mid feat={h.shape}')
|
||||
|
||||
# upsampling
|
||||
for i_level in reversed(range(self.num_resolutions)):
|
||||
for i_block in range(self.num_res_blocks+1):
|
||||
h = self.up[i_level].block[i_block](h, temb)
|
||||
if len(self.up[i_level].attn) > 0:
|
||||
h = self.up[i_level].attn[i_block](h)
|
||||
# print(f'decoder-up feat={h.shape}')
|
||||
if i_level != 0:
|
||||
h = self.up[i_level].upsample(h)
|
||||
# print(f'decoder-upsample feat={h.shape}')
|
||||
|
||||
# end
|
||||
if self.give_pre_end:
|
||||
return h
|
||||
|
||||
h = self.norm_out(h)
|
||||
h = nonlinearity(h)
|
||||
h = self.conv_out(h)
|
||||
# print(f'decoder-conv_out feat={h.shape}')
|
||||
if self.tanh_out:
|
||||
h = torch.tanh(h)
|
||||
return h
|
||||
|
||||
|
||||
class SimpleDecoder(nn.Module):
|
||||
def __init__(self, in_channels, out_channels, *args, **kwargs):
|
||||
super().__init__()
|
||||
self.model = nn.ModuleList([nn.Conv2d(in_channels, in_channels, 1),
|
||||
ResnetBlock(in_channels=in_channels,
|
||||
out_channels=2 * in_channels,
|
||||
temb_channels=0, dropout=0.0),
|
||||
ResnetBlock(in_channels=2 * in_channels,
|
||||
out_channels=4 * in_channels,
|
||||
temb_channels=0, dropout=0.0),
|
||||
ResnetBlock(in_channels=4 * in_channels,
|
||||
out_channels=2 * in_channels,
|
||||
temb_channels=0, dropout=0.0),
|
||||
nn.Conv2d(2*in_channels, in_channels, 1),
|
||||
Upsample(in_channels, with_conv=True)])
|
||||
# end
|
||||
self.norm_out = Normalize(in_channels)
|
||||
self.conv_out = torch.nn.Conv2d(in_channels,
|
||||
out_channels,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1)
|
||||
|
||||
def forward(self, x):
|
||||
for i, layer in enumerate(self.model):
|
||||
if i in [1,2,3]:
|
||||
x = layer(x, None)
|
||||
else:
|
||||
x = layer(x)
|
||||
|
||||
h = self.norm_out(x)
|
||||
h = nonlinearity(h)
|
||||
x = self.conv_out(h)
|
||||
return x
|
||||
|
||||
|
||||
class UpsampleDecoder(nn.Module):
|
||||
def __init__(self, in_channels, out_channels, ch, num_res_blocks, resolution,
|
||||
ch_mult=(2,2), dropout=0.0):
|
||||
super().__init__()
|
||||
# upsampling
|
||||
self.temb_ch = 0
|
||||
self.num_resolutions = len(ch_mult)
|
||||
self.num_res_blocks = num_res_blocks
|
||||
block_in = in_channels
|
||||
curr_res = resolution // 2 ** (self.num_resolutions - 1)
|
||||
self.res_blocks = nn.ModuleList()
|
||||
self.upsample_blocks = nn.ModuleList()
|
||||
for i_level in range(self.num_resolutions):
|
||||
res_block = []
|
||||
block_out = ch * ch_mult[i_level]
|
||||
for i_block in range(self.num_res_blocks + 1):
|
||||
res_block.append(ResnetBlock(in_channels=block_in,
|
||||
out_channels=block_out,
|
||||
temb_channels=self.temb_ch,
|
||||
dropout=dropout))
|
||||
block_in = block_out
|
||||
self.res_blocks.append(nn.ModuleList(res_block))
|
||||
if i_level != self.num_resolutions - 1:
|
||||
self.upsample_blocks.append(Upsample(block_in, True))
|
||||
curr_res = curr_res * 2
|
||||
|
||||
# end
|
||||
self.norm_out = Normalize(block_in)
|
||||
self.conv_out = torch.nn.Conv2d(block_in,
|
||||
out_channels,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1)
|
||||
|
||||
def forward(self, x):
|
||||
# upsampling
|
||||
h = x
|
||||
for k, i_level in enumerate(range(self.num_resolutions)):
|
||||
for i_block in range(self.num_res_blocks + 1):
|
||||
h = self.res_blocks[i_level][i_block](h, None)
|
||||
if i_level != self.num_resolutions - 1:
|
||||
h = self.upsample_blocks[k](h)
|
||||
h = self.norm_out(h)
|
||||
h = nonlinearity(h)
|
||||
h = self.conv_out(h)
|
||||
return h
|
||||
|
||||
|
||||
class LatentRescaler(nn.Module):
|
||||
def __init__(self, factor, in_channels, mid_channels, out_channels, depth=2):
|
||||
super().__init__()
|
||||
# residual block, interpolate, residual block
|
||||
self.factor = factor
|
||||
self.conv_in = nn.Conv2d(in_channels,
|
||||
mid_channels,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1)
|
||||
self.res_block1 = nn.ModuleList([ResnetBlock(in_channels=mid_channels,
|
||||
out_channels=mid_channels,
|
||||
temb_channels=0,
|
||||
dropout=0.0) for _ in range(depth)])
|
||||
self.attn = AttnBlock(mid_channels)
|
||||
self.res_block2 = nn.ModuleList([ResnetBlock(in_channels=mid_channels,
|
||||
out_channels=mid_channels,
|
||||
temb_channels=0,
|
||||
dropout=0.0) for _ in range(depth)])
|
||||
|
||||
self.conv_out = nn.Conv2d(mid_channels,
|
||||
out_channels,
|
||||
kernel_size=1,
|
||||
)
|
||||
|
||||
def forward(self, x):
|
||||
x = self.conv_in(x)
|
||||
for block in self.res_block1:
|
||||
x = block(x, None)
|
||||
x = torch.nn.functional.interpolate(x, size=(int(round(x.shape[2]*self.factor)), int(round(x.shape[3]*self.factor))))
|
||||
x = self.attn(x)
|
||||
for block in self.res_block2:
|
||||
x = block(x, None)
|
||||
x = self.conv_out(x)
|
||||
return x
|
||||
|
||||
|
||||
class MergedRescaleEncoder(nn.Module):
|
||||
def __init__(self, in_channels, ch, resolution, out_ch, num_res_blocks,
|
||||
attn_resolutions, dropout=0.0, resamp_with_conv=True,
|
||||
ch_mult=(1,2,4,8), rescale_factor=1.0, rescale_module_depth=1):
|
||||
super().__init__()
|
||||
intermediate_chn = ch * ch_mult[-1]
|
||||
self.encoder = Encoder(in_channels=in_channels, num_res_blocks=num_res_blocks, ch=ch, ch_mult=ch_mult,
|
||||
z_channels=intermediate_chn, double_z=False, resolution=resolution,
|
||||
attn_resolutions=attn_resolutions, dropout=dropout, resamp_with_conv=resamp_with_conv,
|
||||
out_ch=None)
|
||||
self.rescaler = LatentRescaler(factor=rescale_factor, in_channels=intermediate_chn,
|
||||
mid_channels=intermediate_chn, out_channels=out_ch, depth=rescale_module_depth)
|
||||
|
||||
def forward(self, x):
|
||||
x = self.encoder(x)
|
||||
x = self.rescaler(x)
|
||||
return x
|
||||
|
||||
|
||||
class MergedRescaleDecoder(nn.Module):
|
||||
def __init__(self, z_channels, out_ch, resolution, num_res_blocks, attn_resolutions, ch, ch_mult=(1,2,4,8),
|
||||
dropout=0.0, resamp_with_conv=True, rescale_factor=1.0, rescale_module_depth=1):
|
||||
super().__init__()
|
||||
tmp_chn = z_channels*ch_mult[-1]
|
||||
self.decoder = Decoder(out_ch=out_ch, z_channels=tmp_chn, attn_resolutions=attn_resolutions, dropout=dropout,
|
||||
resamp_with_conv=resamp_with_conv, in_channels=None, num_res_blocks=num_res_blocks,
|
||||
ch_mult=ch_mult, resolution=resolution, ch=ch)
|
||||
self.rescaler = LatentRescaler(factor=rescale_factor, in_channels=z_channels, mid_channels=tmp_chn,
|
||||
out_channels=tmp_chn, depth=rescale_module_depth)
|
||||
|
||||
def forward(self, x):
|
||||
x = self.rescaler(x)
|
||||
x = self.decoder(x)
|
||||
return x
|
||||
|
||||
|
||||
class Upsampler(nn.Module):
|
||||
def __init__(self, in_size, out_size, in_channels, out_channels, ch_mult=2):
|
||||
super().__init__()
|
||||
assert out_size >= in_size
|
||||
num_blocks = int(np.log2(out_size//in_size))+1
|
||||
factor_up = 1.+ (out_size % in_size)
|
||||
print(f"Building {self.__class__.__name__} with in_size: {in_size} --> out_size {out_size} and factor {factor_up}")
|
||||
self.rescaler = LatentRescaler(factor=factor_up, in_channels=in_channels, mid_channels=2*in_channels,
|
||||
out_channels=in_channels)
|
||||
self.decoder = Decoder(out_ch=out_channels, resolution=out_size, z_channels=in_channels, num_res_blocks=2,
|
||||
attn_resolutions=[], in_channels=None, ch=in_channels,
|
||||
ch_mult=[ch_mult for _ in range(num_blocks)])
|
||||
|
||||
def forward(self, x):
|
||||
x = self.rescaler(x)
|
||||
x = self.decoder(x)
|
||||
return x
|
||||
|
||||
|
||||
class Resize(nn.Module):
|
||||
def __init__(self, in_channels=None, learned=False, mode="bilinear"):
|
||||
super().__init__()
|
||||
self.with_conv = learned
|
||||
self.mode = mode
|
||||
if self.with_conv:
|
||||
print(f"Note: {self.__class__.__name} uses learned downsampling and will ignore the fixed {mode} mode")
|
||||
raise NotImplementedError()
|
||||
assert in_channels is not None
|
||||
# no asymmetric padding in torch conv, must do it ourselves
|
||||
self.conv = torch.nn.Conv2d(in_channels,
|
||||
in_channels,
|
||||
kernel_size=4,
|
||||
stride=2,
|
||||
padding=1)
|
||||
|
||||
def forward(self, x, scale_factor=1.0):
|
||||
if scale_factor==1.0:
|
||||
return x
|
||||
else:
|
||||
x = torch.nn.functional.interpolate(x, mode=self.mode, align_corners=False, scale_factor=scale_factor)
|
||||
return x
|
||||
|
||||
class FirstStagePostProcessor(nn.Module):
|
||||
|
||||
def __init__(self, ch_mult:list, in_channels,
|
||||
pretrained_model:nn.Module=None,
|
||||
reshape=False,
|
||||
n_channels=None,
|
||||
dropout=0.,
|
||||
pretrained_config=None):
|
||||
super().__init__()
|
||||
if pretrained_config is None:
|
||||
assert pretrained_model is not None, 'Either "pretrained_model" or "pretrained_config" must not be None'
|
||||
self.pretrained_model = pretrained_model
|
||||
else:
|
||||
assert pretrained_config is not None, 'Either "pretrained_model" or "pretrained_config" must not be None'
|
||||
self.instantiate_pretrained(pretrained_config)
|
||||
|
||||
self.do_reshape = reshape
|
||||
|
||||
if n_channels is None:
|
||||
n_channels = self.pretrained_model.encoder.ch
|
||||
|
||||
self.proj_norm = Normalize(in_channels,num_groups=in_channels//2)
|
||||
self.proj = nn.Conv2d(in_channels,n_channels,kernel_size=3,
|
||||
stride=1,padding=1)
|
||||
|
||||
blocks = []
|
||||
downs = []
|
||||
ch_in = n_channels
|
||||
for m in ch_mult:
|
||||
blocks.append(ResnetBlock(in_channels=ch_in,out_channels=m*n_channels,dropout=dropout))
|
||||
ch_in = m * n_channels
|
||||
downs.append(Downsample(ch_in, with_conv=False))
|
||||
|
||||
self.model = nn.ModuleList(blocks)
|
||||
self.downsampler = nn.ModuleList(downs)
|
||||
|
||||
|
||||
def instantiate_pretrained(self, config):
|
||||
model = instantiate_from_config(config)
|
||||
self.pretrained_model = model.eval()
|
||||
# self.pretrained_model.train = False
|
||||
for param in self.pretrained_model.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
|
||||
@torch.no_grad()
|
||||
def encode_with_pretrained(self,x):
|
||||
c = self.pretrained_model.encode(x)
|
||||
if isinstance(c, DiagonalGaussianDistribution):
|
||||
c = c.mode()
|
||||
return c
|
||||
|
||||
def forward(self,x):
|
||||
z_fs = self.encode_with_pretrained(x)
|
||||
z = self.proj_norm(z_fs)
|
||||
z = self.proj(z)
|
||||
z = nonlinearity(z)
|
||||
|
||||
for submodel, downmodel in zip(self.model,self.downsampler):
|
||||
z = submodel(z,temb=None)
|
||||
z = downmodel(z)
|
||||
|
||||
if self.do_reshape:
|
||||
z = rearrange(z,'b c h w -> b (h w) c')
|
||||
return z
|
||||
@@ -0,0 +1,603 @@
|
||||
from functools import partial
|
||||
from abc import abstractmethod
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from einops import rearrange
|
||||
import torch.nn.functional as F
|
||||
from ....lvdm.models.utils_diffusion import timestep_embedding
|
||||
from ....lvdm.common import checkpoint
|
||||
from ....lvdm.basics import (
|
||||
zero_module,
|
||||
conv_nd,
|
||||
linear,
|
||||
avg_pool_nd,
|
||||
normalization
|
||||
)
|
||||
from ....lvdm.modules.attention import SpatialTransformer, TemporalTransformer
|
||||
|
||||
|
||||
class TimestepBlock(nn.Module):
|
||||
"""
|
||||
Any module where forward() takes timestep embeddings as a second argument.
|
||||
"""
|
||||
@abstractmethod
|
||||
def forward(self, x, emb):
|
||||
"""
|
||||
Apply the module to `x` given `emb` timestep embeddings.
|
||||
"""
|
||||
|
||||
|
||||
class TimestepEmbedSequential(nn.Sequential, TimestepBlock):
|
||||
"""
|
||||
A sequential module that passes timestep embeddings to the children that
|
||||
support it as an extra input.
|
||||
"""
|
||||
|
||||
def forward(self, x, emb, context=None, batch_size=None):
|
||||
for layer in self:
|
||||
if isinstance(layer, TimestepBlock):
|
||||
x = layer(x, emb, batch_size=batch_size)
|
||||
elif isinstance(layer, SpatialTransformer):
|
||||
x = layer(x, context)
|
||||
elif isinstance(layer, TemporalTransformer):
|
||||
x = rearrange(x, '(b f) c h w -> b c f h w', b=batch_size)
|
||||
x = layer(x, context)
|
||||
x = rearrange(x, 'b c f h w -> (b f) c h w')
|
||||
else:
|
||||
x = layer(x)
|
||||
return x
|
||||
|
||||
|
||||
class Downsample(nn.Module):
|
||||
"""
|
||||
A downsampling layer with an optional convolution.
|
||||
:param channels: channels in the inputs and outputs.
|
||||
:param use_conv: a bool determining if a convolution is applied.
|
||||
:param dims: determines if the signal is 1D, 2D, or 3D. If 3D, then
|
||||
downsampling occurs in the inner-two dimensions.
|
||||
"""
|
||||
|
||||
def __init__(self, channels, use_conv, dims=2, out_channels=None, padding=1):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.out_channels = out_channels or channels
|
||||
self.use_conv = use_conv
|
||||
self.dims = dims
|
||||
stride = 2 if dims != 3 else (1, 2, 2)
|
||||
if use_conv:
|
||||
self.op = conv_nd(
|
||||
dims, self.channels, self.out_channels, 3, stride=stride, padding=padding
|
||||
)
|
||||
else:
|
||||
assert self.channels == self.out_channels
|
||||
self.op = avg_pool_nd(dims, kernel_size=stride, stride=stride)
|
||||
|
||||
def forward(self, x):
|
||||
assert x.shape[1] == self.channels
|
||||
return self.op(x)
|
||||
|
||||
|
||||
class Upsample(nn.Module):
|
||||
"""
|
||||
An upsampling layer with an optional convolution.
|
||||
:param channels: channels in the inputs and outputs.
|
||||
:param use_conv: a bool determining if a convolution is applied.
|
||||
:param dims: determines if the signal is 1D, 2D, or 3D. If 3D, then
|
||||
upsampling occurs in the inner-two dimensions.
|
||||
"""
|
||||
|
||||
def __init__(self, channels, use_conv, dims=2, out_channels=None, padding=1):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.out_channels = out_channels or channels
|
||||
self.use_conv = use_conv
|
||||
self.dims = dims
|
||||
if use_conv:
|
||||
self.conv = conv_nd(dims, self.channels, self.out_channels, 3, padding=padding)
|
||||
|
||||
def forward(self, x):
|
||||
assert x.shape[1] == self.channels
|
||||
if self.dims == 3:
|
||||
x = F.interpolate(x, (x.shape[2], x.shape[3] * 2, x.shape[4] * 2), mode='nearest')
|
||||
else:
|
||||
x = F.interpolate(x, scale_factor=2, mode='nearest')
|
||||
if self.use_conv:
|
||||
x = self.conv(x)
|
||||
return x
|
||||
|
||||
|
||||
class ResBlock(TimestepBlock):
|
||||
"""
|
||||
A residual block that can optionally change the number of channels.
|
||||
:param channels: the number of input channels.
|
||||
:param emb_channels: the number of timestep embedding channels.
|
||||
:param dropout: the rate of dropout.
|
||||
:param out_channels: if specified, the number of out channels.
|
||||
:param use_conv: if True and out_channels is specified, use a spatial
|
||||
convolution instead of a smaller 1x1 convolution to change the
|
||||
channels in the skip connection.
|
||||
:param dims: determines if the signal is 1D, 2D, or 3D.
|
||||
:param up: if True, use this block for upsampling.
|
||||
:param down: if True, use this block for downsampling.
|
||||
:param use_temporal_conv: if True, use the temporal convolution.
|
||||
:param use_image_dataset: if True, the temporal parameters will not be optimized.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
channels,
|
||||
emb_channels,
|
||||
dropout,
|
||||
out_channels=None,
|
||||
use_scale_shift_norm=False,
|
||||
dims=2,
|
||||
use_checkpoint=False,
|
||||
use_conv=False,
|
||||
up=False,
|
||||
down=False,
|
||||
use_temporal_conv=False,
|
||||
tempspatial_aware=False
|
||||
):
|
||||
super().__init__()
|
||||
self.channels = channels
|
||||
self.emb_channels = emb_channels
|
||||
self.dropout = dropout
|
||||
self.out_channels = out_channels or channels
|
||||
self.use_conv = use_conv
|
||||
self.use_checkpoint = use_checkpoint
|
||||
self.use_scale_shift_norm = use_scale_shift_norm
|
||||
self.use_temporal_conv = use_temporal_conv
|
||||
|
||||
self.in_layers = nn.Sequential(
|
||||
normalization(channels),
|
||||
nn.SiLU(),
|
||||
conv_nd(dims, channels, self.out_channels, 3, padding=1),
|
||||
)
|
||||
|
||||
self.updown = up or down
|
||||
|
||||
if up:
|
||||
self.h_upd = Upsample(channels, False, dims)
|
||||
self.x_upd = Upsample(channels, False, dims)
|
||||
elif down:
|
||||
self.h_upd = Downsample(channels, False, dims)
|
||||
self.x_upd = Downsample(channels, False, dims)
|
||||
else:
|
||||
self.h_upd = self.x_upd = nn.Identity()
|
||||
|
||||
self.emb_layers = nn.Sequential(
|
||||
nn.SiLU(),
|
||||
nn.Linear(
|
||||
emb_channels,
|
||||
2 * self.out_channels if use_scale_shift_norm else self.out_channels,
|
||||
),
|
||||
)
|
||||
self.out_layers = nn.Sequential(
|
||||
normalization(self.out_channels),
|
||||
nn.SiLU(),
|
||||
nn.Dropout(p=dropout),
|
||||
zero_module(nn.Conv2d(self.out_channels, self.out_channels, 3, padding=1)),
|
||||
)
|
||||
|
||||
if self.out_channels == channels:
|
||||
self.skip_connection = nn.Identity()
|
||||
elif use_conv:
|
||||
self.skip_connection = conv_nd(dims, channels, self.out_channels, 3, padding=1)
|
||||
else:
|
||||
self.skip_connection = conv_nd(dims, channels, self.out_channels, 1)
|
||||
|
||||
if self.use_temporal_conv:
|
||||
self.temopral_conv = TemporalConvBlock(
|
||||
self.out_channels,
|
||||
self.out_channels,
|
||||
dropout=0.1,
|
||||
spatial_aware=tempspatial_aware
|
||||
)
|
||||
|
||||
def forward(self, x, emb, batch_size=None):
|
||||
"""
|
||||
Apply the block to a Tensor, conditioned on a timestep embedding.
|
||||
:param x: an [N x C x ...] Tensor of features.
|
||||
:param emb: an [N x emb_channels] Tensor of timestep embeddings.
|
||||
:return: an [N x C x ...] Tensor of outputs.
|
||||
"""
|
||||
input_tuple = (x, emb)
|
||||
if batch_size:
|
||||
forward_batchsize = partial(self._forward, batch_size=batch_size)
|
||||
return checkpoint(forward_batchsize, input_tuple, self.parameters(), self.use_checkpoint)
|
||||
return checkpoint(self._forward, input_tuple, self.parameters(), self.use_checkpoint)
|
||||
|
||||
def _forward(self, x, emb, batch_size=None):
|
||||
if self.updown:
|
||||
in_rest, in_conv = self.in_layers[:-1], self.in_layers[-1]
|
||||
h = in_rest(x)
|
||||
h = self.h_upd(h)
|
||||
x = self.x_upd(x)
|
||||
h = in_conv(h)
|
||||
else:
|
||||
h = self.in_layers(x)
|
||||
emb_out = self.emb_layers(emb).type(h.dtype)
|
||||
while len(emb_out.shape) < len(h.shape):
|
||||
emb_out = emb_out[..., None]
|
||||
if self.use_scale_shift_norm:
|
||||
out_norm, out_rest = self.out_layers[0], self.out_layers[1:]
|
||||
scale, shift = torch.chunk(emb_out, 2, dim=1)
|
||||
h = out_norm(h) * (1 + scale) + shift
|
||||
h = out_rest(h)
|
||||
else:
|
||||
h = h + emb_out
|
||||
h = self.out_layers(h)
|
||||
h = self.skip_connection(x) + h
|
||||
|
||||
if self.use_temporal_conv and batch_size:
|
||||
h = rearrange(h, '(b t) c h w -> b c t h w', b=batch_size)
|
||||
h = self.temopral_conv(h)
|
||||
h = rearrange(h, 'b c t h w -> (b t) c h w')
|
||||
return h
|
||||
|
||||
|
||||
class TemporalConvBlock(nn.Module):
|
||||
"""
|
||||
Adapted from modelscope: https://github.com/modelscope/modelscope/blob/master/modelscope/models/multi_modal/video_synthesis/unet_sd.py
|
||||
"""
|
||||
def __init__(self, in_channels, out_channels=None, dropout=0.0, spatial_aware=False):
|
||||
super(TemporalConvBlock, self).__init__()
|
||||
if out_channels is None:
|
||||
out_channels = in_channels
|
||||
self.in_channels = in_channels
|
||||
self.out_channels = out_channels
|
||||
th_kernel_shape = (3, 1, 1) if not spatial_aware else (3, 3, 1)
|
||||
th_padding_shape = (1, 0, 0) if not spatial_aware else (1, 1, 0)
|
||||
tw_kernel_shape = (3, 1, 1) if not spatial_aware else (3, 1, 3)
|
||||
tw_padding_shape = (1, 0, 0) if not spatial_aware else (1, 0, 1)
|
||||
|
||||
# conv layers
|
||||
self.conv1 = nn.Sequential(
|
||||
nn.GroupNorm(32, in_channels), nn.SiLU(),
|
||||
nn.Conv3d(in_channels, out_channels, th_kernel_shape, padding=th_padding_shape))
|
||||
self.conv2 = nn.Sequential(
|
||||
nn.GroupNorm(32, out_channels), nn.SiLU(), nn.Dropout(dropout),
|
||||
nn.Conv3d(out_channels, in_channels, tw_kernel_shape, padding=tw_padding_shape))
|
||||
self.conv3 = nn.Sequential(
|
||||
nn.GroupNorm(32, out_channels), nn.SiLU(), nn.Dropout(dropout),
|
||||
nn.Conv3d(out_channels, in_channels, th_kernel_shape, padding=th_padding_shape))
|
||||
self.conv4 = nn.Sequential(
|
||||
nn.GroupNorm(32, out_channels), nn.SiLU(), nn.Dropout(dropout),
|
||||
nn.Conv3d(out_channels, in_channels, tw_kernel_shape, padding=tw_padding_shape))
|
||||
|
||||
# zero out the last layer params,so the conv block is identity
|
||||
nn.init.zeros_(self.conv4[-1].weight)
|
||||
nn.init.zeros_(self.conv4[-1].bias)
|
||||
|
||||
def forward(self, x):
|
||||
identity = x
|
||||
x = self.conv1(x)
|
||||
x = self.conv2(x)
|
||||
x = self.conv3(x)
|
||||
x = self.conv4(x)
|
||||
|
||||
return identity + x
|
||||
|
||||
class UNetModel(nn.Module):
|
||||
"""
|
||||
The full UNet model with attention and timestep embedding.
|
||||
:param in_channels: in_channels in the input Tensor.
|
||||
:param model_channels: base channel count for the model.
|
||||
:param out_channels: channels in the output Tensor.
|
||||
:param num_res_blocks: number of residual blocks per downsample.
|
||||
:param attention_resolutions: a collection of downsample rates at which
|
||||
attention will take place. May be a set, list, or tuple.
|
||||
For example, if this contains 4, then at 4x downsampling, attention
|
||||
will be used.
|
||||
:param dropout: the dropout probability.
|
||||
:param channel_mult: channel multiplier for each level of the UNet.
|
||||
:param conv_resample: if True, use learned convolutions for upsampling and
|
||||
downsampling.
|
||||
:param dims: determines if the signal is 1D, 2D, or 3D.
|
||||
:param num_classes: if specified (as an int), then this model will be
|
||||
class-conditional with `num_classes` classes.
|
||||
:param use_checkpoint: use gradient checkpointing to reduce memory usage.
|
||||
:param num_heads: the number of attention heads in each attention layer.
|
||||
:param num_heads_channels: if specified, ignore num_heads and instead use
|
||||
a fixed channel width per attention head.
|
||||
:param num_heads_upsample: works with num_heads to set a different number
|
||||
of heads for upsampling. Deprecated.
|
||||
:param use_scale_shift_norm: use a FiLM-like conditioning mechanism.
|
||||
:param resblock_updown: use residual blocks for up/downsampling.
|
||||
:param use_new_attention_order: use a different attention pattern for potentially
|
||||
increased efficiency.
|
||||
"""
|
||||
|
||||
def __init__(self,
|
||||
in_channels,
|
||||
model_channels,
|
||||
out_channels,
|
||||
num_res_blocks,
|
||||
attention_resolutions,
|
||||
dropout=0.0,
|
||||
channel_mult=(1, 2, 4, 8),
|
||||
conv_resample=True,
|
||||
dims=2,
|
||||
context_dim=None,
|
||||
use_scale_shift_norm=False,
|
||||
resblock_updown=False,
|
||||
num_heads=-1,
|
||||
num_head_channels=-1,
|
||||
transformer_depth=1,
|
||||
use_linear=False,
|
||||
use_checkpoint=False,
|
||||
temporal_conv=False,
|
||||
tempspatial_aware=False,
|
||||
temporal_attention=True,
|
||||
use_relative_position=True,
|
||||
use_causal_attention=False,
|
||||
temporal_length=None,
|
||||
use_fp16=False,
|
||||
addition_attention=False,
|
||||
temporal_selfatt_only=True,
|
||||
image_cross_attention=False,
|
||||
image_cross_attention_scale_learnable=False,
|
||||
default_fs=4,
|
||||
fs_condition=False,
|
||||
):
|
||||
super(UNetModel, self).__init__()
|
||||
if num_heads == -1:
|
||||
assert num_head_channels != -1, 'Either num_heads or num_head_channels has to be set'
|
||||
if num_head_channels == -1:
|
||||
assert num_heads != -1, 'Either num_heads or num_head_channels has to be set'
|
||||
|
||||
self.in_channels = in_channels
|
||||
self.model_channels = model_channels
|
||||
self.out_channels = out_channels
|
||||
self.num_res_blocks = num_res_blocks
|
||||
self.attention_resolutions = attention_resolutions
|
||||
self.dropout = dropout
|
||||
self.channel_mult = channel_mult
|
||||
self.conv_resample = conv_resample
|
||||
self.temporal_attention = temporal_attention
|
||||
time_embed_dim = model_channels * 4
|
||||
self.use_checkpoint = use_checkpoint
|
||||
self.dtype = torch.float16 if use_fp16 else torch.float32
|
||||
temporal_self_att_only = True
|
||||
self.addition_attention = addition_attention
|
||||
self.temporal_length = temporal_length
|
||||
self.image_cross_attention = image_cross_attention
|
||||
self.image_cross_attention_scale_learnable = image_cross_attention_scale_learnable
|
||||
self.default_fs = default_fs
|
||||
self.fs_condition = fs_condition
|
||||
|
||||
## Time embedding blocks
|
||||
self.time_embed = nn.Sequential(
|
||||
linear(model_channels, time_embed_dim),
|
||||
nn.SiLU(),
|
||||
linear(time_embed_dim, time_embed_dim),
|
||||
)
|
||||
if fs_condition:
|
||||
self.fps_embedding = nn.Sequential(
|
||||
linear(model_channels, time_embed_dim),
|
||||
nn.SiLU(),
|
||||
linear(time_embed_dim, time_embed_dim),
|
||||
)
|
||||
nn.init.zeros_(self.fps_embedding[-1].weight)
|
||||
nn.init.zeros_(self.fps_embedding[-1].bias)
|
||||
## Input Block
|
||||
self.input_blocks = nn.ModuleList(
|
||||
[
|
||||
TimestepEmbedSequential(conv_nd(dims, in_channels, model_channels, 3, padding=1))
|
||||
]
|
||||
)
|
||||
if self.addition_attention:
|
||||
self.init_attn=TimestepEmbedSequential(
|
||||
TemporalTransformer(
|
||||
model_channels,
|
||||
n_heads=8,
|
||||
d_head=num_head_channels,
|
||||
depth=transformer_depth,
|
||||
context_dim=context_dim,
|
||||
use_checkpoint=use_checkpoint, only_self_att=temporal_selfatt_only,
|
||||
causal_attention=False, relative_position=use_relative_position,
|
||||
temporal_length=temporal_length))
|
||||
|
||||
input_block_chans = [model_channels]
|
||||
ch = model_channels
|
||||
ds = 1
|
||||
for level, mult in enumerate(channel_mult):
|
||||
for _ in range(num_res_blocks):
|
||||
layers = [
|
||||
ResBlock(ch, time_embed_dim, dropout,
|
||||
out_channels=mult * model_channels, dims=dims, use_checkpoint=use_checkpoint,
|
||||
use_scale_shift_norm=use_scale_shift_norm, tempspatial_aware=tempspatial_aware,
|
||||
use_temporal_conv=temporal_conv
|
||||
)
|
||||
]
|
||||
ch = mult * model_channels
|
||||
if ds in attention_resolutions:
|
||||
if num_head_channels == -1:
|
||||
dim_head = ch // num_heads
|
||||
else:
|
||||
num_heads = ch // num_head_channels
|
||||
dim_head = num_head_channels
|
||||
layers.append(
|
||||
SpatialTransformer(ch, num_heads, dim_head,
|
||||
depth=transformer_depth, context_dim=context_dim, use_linear=use_linear,
|
||||
use_checkpoint=use_checkpoint, disable_self_attn=False,
|
||||
video_length=temporal_length, image_cross_attention=self.image_cross_attention,
|
||||
image_cross_attention_scale_learnable=self.image_cross_attention_scale_learnable,
|
||||
)
|
||||
)
|
||||
if self.temporal_attention:
|
||||
layers.append(
|
||||
TemporalTransformer(ch, num_heads, dim_head,
|
||||
depth=transformer_depth, context_dim=context_dim, use_linear=use_linear,
|
||||
use_checkpoint=use_checkpoint, only_self_att=temporal_self_att_only,
|
||||
causal_attention=use_causal_attention, relative_position=use_relative_position,
|
||||
temporal_length=temporal_length
|
||||
)
|
||||
)
|
||||
self.input_blocks.append(TimestepEmbedSequential(*layers))
|
||||
input_block_chans.append(ch)
|
||||
if level != len(channel_mult) - 1:
|
||||
out_ch = ch
|
||||
self.input_blocks.append(
|
||||
TimestepEmbedSequential(
|
||||
ResBlock(ch, time_embed_dim, dropout,
|
||||
out_channels=out_ch, dims=dims, use_checkpoint=use_checkpoint,
|
||||
use_scale_shift_norm=use_scale_shift_norm,
|
||||
down=True
|
||||
)
|
||||
if resblock_updown
|
||||
else Downsample(ch, conv_resample, dims=dims, out_channels=out_ch)
|
||||
)
|
||||
)
|
||||
ch = out_ch
|
||||
input_block_chans.append(ch)
|
||||
ds *= 2
|
||||
|
||||
if num_head_channels == -1:
|
||||
dim_head = ch // num_heads
|
||||
else:
|
||||
num_heads = ch // num_head_channels
|
||||
dim_head = num_head_channels
|
||||
layers = [
|
||||
ResBlock(ch, time_embed_dim, dropout,
|
||||
dims=dims, use_checkpoint=use_checkpoint,
|
||||
use_scale_shift_norm=use_scale_shift_norm, tempspatial_aware=tempspatial_aware,
|
||||
use_temporal_conv=temporal_conv
|
||||
),
|
||||
SpatialTransformer(ch, num_heads, dim_head,
|
||||
depth=transformer_depth, context_dim=context_dim, use_linear=use_linear,
|
||||
use_checkpoint=use_checkpoint, disable_self_attn=False, video_length=temporal_length,
|
||||
image_cross_attention=self.image_cross_attention,image_cross_attention_scale_learnable=self.image_cross_attention_scale_learnable
|
||||
)
|
||||
]
|
||||
if self.temporal_attention:
|
||||
layers.append(
|
||||
TemporalTransformer(ch, num_heads, dim_head,
|
||||
depth=transformer_depth, context_dim=context_dim, use_linear=use_linear,
|
||||
use_checkpoint=use_checkpoint, only_self_att=temporal_self_att_only,
|
||||
causal_attention=use_causal_attention, relative_position=use_relative_position,
|
||||
temporal_length=temporal_length
|
||||
)
|
||||
)
|
||||
layers.append(
|
||||
ResBlock(ch, time_embed_dim, dropout,
|
||||
dims=dims, use_checkpoint=use_checkpoint,
|
||||
use_scale_shift_norm=use_scale_shift_norm, tempspatial_aware=tempspatial_aware,
|
||||
use_temporal_conv=temporal_conv
|
||||
)
|
||||
)
|
||||
|
||||
## Middle Block
|
||||
self.middle_block = TimestepEmbedSequential(*layers)
|
||||
|
||||
## Output Block
|
||||
self.output_blocks = nn.ModuleList([])
|
||||
for level, mult in list(enumerate(channel_mult))[::-1]:
|
||||
for i in range(num_res_blocks + 1):
|
||||
ich = input_block_chans.pop()
|
||||
layers = [
|
||||
ResBlock(ch + ich, time_embed_dim, dropout,
|
||||
out_channels=mult * model_channels, dims=dims, use_checkpoint=use_checkpoint,
|
||||
use_scale_shift_norm=use_scale_shift_norm, tempspatial_aware=tempspatial_aware,
|
||||
use_temporal_conv=temporal_conv
|
||||
)
|
||||
]
|
||||
ch = model_channels * mult
|
||||
if ds in attention_resolutions:
|
||||
if num_head_channels == -1:
|
||||
dim_head = ch // num_heads
|
||||
else:
|
||||
num_heads = ch // num_head_channels
|
||||
dim_head = num_head_channels
|
||||
layers.append(
|
||||
SpatialTransformer(ch, num_heads, dim_head,
|
||||
depth=transformer_depth, context_dim=context_dim, use_linear=use_linear,
|
||||
use_checkpoint=use_checkpoint, disable_self_attn=False, video_length=temporal_length,
|
||||
image_cross_attention=self.image_cross_attention,image_cross_attention_scale_learnable=self.image_cross_attention_scale_learnable
|
||||
)
|
||||
)
|
||||
if self.temporal_attention:
|
||||
layers.append(
|
||||
TemporalTransformer(ch, num_heads, dim_head,
|
||||
depth=transformer_depth, context_dim=context_dim, use_linear=use_linear,
|
||||
use_checkpoint=use_checkpoint, only_self_att=temporal_self_att_only,
|
||||
causal_attention=use_causal_attention, relative_position=use_relative_position,
|
||||
temporal_length=temporal_length
|
||||
)
|
||||
)
|
||||
if level and i == num_res_blocks:
|
||||
out_ch = ch
|
||||
layers.append(
|
||||
ResBlock(ch, time_embed_dim, dropout,
|
||||
out_channels=out_ch, dims=dims, use_checkpoint=use_checkpoint,
|
||||
use_scale_shift_norm=use_scale_shift_norm,
|
||||
up=True
|
||||
)
|
||||
if resblock_updown
|
||||
else Upsample(ch, conv_resample, dims=dims, out_channels=out_ch)
|
||||
)
|
||||
ds //= 2
|
||||
self.output_blocks.append(TimestepEmbedSequential(*layers))
|
||||
|
||||
self.out = nn.Sequential(
|
||||
normalization(ch),
|
||||
nn.SiLU(),
|
||||
zero_module(conv_nd(dims, model_channels, out_channels, 3, padding=1)),
|
||||
)
|
||||
|
||||
def forward(self, x, timesteps, context=None, features_adapter=None, fs=None, **kwargs):
|
||||
b,_,t,_,_ = x.shape
|
||||
t_emb = timestep_embedding(timesteps, self.model_channels, repeat_only=False).type(x.dtype)
|
||||
emb = self.time_embed(t_emb)
|
||||
|
||||
## repeat t times for context [(b t) 77 768] & time embedding
|
||||
## check if we use per-frame image conditioning
|
||||
_, l_context, _ = context.shape
|
||||
if l_context == 77 + t*16: ## !!! HARD CODE here
|
||||
context_text, context_img = context[:,:77,:], context[:,77:,:]
|
||||
context_text = context_text.repeat_interleave(repeats=t, dim=0)
|
||||
context_img = rearrange(context_img, 'b (t l) c -> (b t) l c', t=t)
|
||||
context = torch.cat([context_text, context_img], dim=1)
|
||||
else:
|
||||
context = context.repeat_interleave(repeats=t, dim=0)
|
||||
emb = emb.repeat_interleave(repeats=t, dim=0)
|
||||
|
||||
## always in shape (b t) c h w, except for temporal layer
|
||||
x = rearrange(x, 'b c t h w -> (b t) c h w')
|
||||
|
||||
## combine emb
|
||||
if self.fs_condition:
|
||||
if fs is None:
|
||||
fs = torch.tensor(
|
||||
[self.default_fs] * b, dtype=torch.long, device=x.device)
|
||||
fs_emb = timestep_embedding(fs, self.model_channels, repeat_only=False).type(x.dtype)
|
||||
|
||||
fs_embed = self.fps_embedding(fs_emb)
|
||||
fs_embed = fs_embed.repeat_interleave(repeats=t, dim=0)
|
||||
emb = emb + fs_embed
|
||||
|
||||
h = x.type(self.dtype)
|
||||
adapter_idx = 0
|
||||
hs = []
|
||||
for id, module in enumerate(self.input_blocks):
|
||||
h = module(h, emb, context=context, batch_size=b)
|
||||
if id ==0 and self.addition_attention:
|
||||
h = self.init_attn(h, emb, context=context, batch_size=b)
|
||||
## plug-in adapter features
|
||||
if ((id+1)%3 == 0) and features_adapter is not None:
|
||||
h = h + features_adapter[adapter_idx]
|
||||
adapter_idx += 1
|
||||
hs.append(h)
|
||||
if features_adapter is not None:
|
||||
assert len(features_adapter)==adapter_idx, 'Wrong features_adapter'
|
||||
|
||||
h = self.middle_block(h, emb, context=context, batch_size=b)
|
||||
for module in self.output_blocks:
|
||||
h = torch.cat([h, hs.pop()], dim=1)
|
||||
h = module(h, emb, context=context, batch_size=b)
|
||||
h = h.type(x.dtype)
|
||||
y = self.out(h)
|
||||
|
||||
# reshape back to (b c t h w)
|
||||
y = rearrange(y, '(b t) c h w -> b c t h w', b=b)
|
||||
return y
|
||||
@@ -0,0 +1,639 @@
|
||||
"""shout-out to https://github.com/lucidrains/x-transformers/tree/main/x_transformers"""
|
||||
from functools import partial
|
||||
from inspect import isfunction
|
||||
from collections import namedtuple
|
||||
from einops import rearrange, repeat
|
||||
import torch
|
||||
from torch import nn, einsum
|
||||
import torch.nn.functional as F
|
||||
|
||||
# constants
|
||||
DEFAULT_DIM_HEAD = 64
|
||||
|
||||
Intermediates = namedtuple('Intermediates', [
|
||||
'pre_softmax_attn',
|
||||
'post_softmax_attn'
|
||||
])
|
||||
|
||||
LayerIntermediates = namedtuple('Intermediates', [
|
||||
'hiddens',
|
||||
'attn_intermediates'
|
||||
])
|
||||
|
||||
|
||||
class AbsolutePositionalEmbedding(nn.Module):
|
||||
def __init__(self, dim, max_seq_len):
|
||||
super().__init__()
|
||||
self.emb = nn.Embedding(max_seq_len, dim)
|
||||
self.init_()
|
||||
|
||||
def init_(self):
|
||||
nn.init.normal_(self.emb.weight, std=0.02)
|
||||
|
||||
def forward(self, x):
|
||||
n = torch.arange(x.shape[1], device=x.device)
|
||||
return self.emb(n)[None, :, :]
|
||||
|
||||
|
||||
class FixedPositionalEmbedding(nn.Module):
|
||||
def __init__(self, dim):
|
||||
super().__init__()
|
||||
inv_freq = 1. / (10000 ** (torch.arange(0, dim, 2).float() / dim))
|
||||
self.register_buffer('inv_freq', inv_freq)
|
||||
|
||||
def forward(self, x, seq_dim=1, offset=0):
|
||||
t = torch.arange(x.shape[seq_dim], device=x.device).type_as(self.inv_freq) + offset
|
||||
sinusoid_inp = torch.einsum('i , j -> i j', t, self.inv_freq)
|
||||
emb = torch.cat((sinusoid_inp.sin(), sinusoid_inp.cos()), dim=-1)
|
||||
return emb[None, :, :]
|
||||
|
||||
|
||||
# helpers
|
||||
|
||||
def exists(val):
|
||||
return val is not None
|
||||
|
||||
|
||||
def default(val, d):
|
||||
if exists(val):
|
||||
return val
|
||||
return d() if isfunction(d) else d
|
||||
|
||||
|
||||
def always(val):
|
||||
def inner(*args, **kwargs):
|
||||
return val
|
||||
return inner
|
||||
|
||||
|
||||
def not_equals(val):
|
||||
def inner(x):
|
||||
return x != val
|
||||
return inner
|
||||
|
||||
|
||||
def equals(val):
|
||||
def inner(x):
|
||||
return x == val
|
||||
return inner
|
||||
|
||||
|
||||
def max_neg_value(tensor):
|
||||
return -torch.finfo(tensor.dtype).max
|
||||
|
||||
|
||||
# keyword argument helpers
|
||||
|
||||
def pick_and_pop(keys, d):
|
||||
values = list(map(lambda key: d.pop(key), keys))
|
||||
return dict(zip(keys, values))
|
||||
|
||||
|
||||
def group_dict_by_key(cond, d):
|
||||
return_val = [dict(), dict()]
|
||||
for key in d.keys():
|
||||
match = bool(cond(key))
|
||||
ind = int(not match)
|
||||
return_val[ind][key] = d[key]
|
||||
return (*return_val,)
|
||||
|
||||
|
||||
def string_begins_with(prefix, str):
|
||||
return str.startswith(prefix)
|
||||
|
||||
|
||||
def group_by_key_prefix(prefix, d):
|
||||
return group_dict_by_key(partial(string_begins_with, prefix), d)
|
||||
|
||||
|
||||
def groupby_prefix_and_trim(prefix, d):
|
||||
kwargs_with_prefix, kwargs = group_dict_by_key(partial(string_begins_with, prefix), d)
|
||||
kwargs_without_prefix = dict(map(lambda x: (x[0][len(prefix):], x[1]), tuple(kwargs_with_prefix.items())))
|
||||
return kwargs_without_prefix, kwargs
|
||||
|
||||
|
||||
# classes
|
||||
class Scale(nn.Module):
|
||||
def __init__(self, value, fn):
|
||||
super().__init__()
|
||||
self.value = value
|
||||
self.fn = fn
|
||||
|
||||
def forward(self, x, **kwargs):
|
||||
x, *rest = self.fn(x, **kwargs)
|
||||
return (x * self.value, *rest)
|
||||
|
||||
|
||||
class Rezero(nn.Module):
|
||||
def __init__(self, fn):
|
||||
super().__init__()
|
||||
self.fn = fn
|
||||
self.g = nn.Parameter(torch.zeros(1))
|
||||
|
||||
def forward(self, x, **kwargs):
|
||||
x, *rest = self.fn(x, **kwargs)
|
||||
return (x * self.g, *rest)
|
||||
|
||||
|
||||
class ScaleNorm(nn.Module):
|
||||
def __init__(self, dim, eps=1e-5):
|
||||
super().__init__()
|
||||
self.scale = dim ** -0.5
|
||||
self.eps = eps
|
||||
self.g = nn.Parameter(torch.ones(1))
|
||||
|
||||
def forward(self, x):
|
||||
norm = torch.norm(x, dim=-1, keepdim=True) * self.scale
|
||||
return x / norm.clamp(min=self.eps) * self.g
|
||||
|
||||
|
||||
class RMSNorm(nn.Module):
|
||||
def __init__(self, dim, eps=1e-8):
|
||||
super().__init__()
|
||||
self.scale = dim ** -0.5
|
||||
self.eps = eps
|
||||
self.g = nn.Parameter(torch.ones(dim))
|
||||
|
||||
def forward(self, x):
|
||||
norm = torch.norm(x, dim=-1, keepdim=True) * self.scale
|
||||
return x / norm.clamp(min=self.eps) * self.g
|
||||
|
||||
|
||||
class Residual(nn.Module):
|
||||
def forward(self, x, residual):
|
||||
return x + residual
|
||||
|
||||
|
||||
class GRUGating(nn.Module):
|
||||
def __init__(self, dim):
|
||||
super().__init__()
|
||||
self.gru = nn.GRUCell(dim, dim)
|
||||
|
||||
def forward(self, x, residual):
|
||||
gated_output = self.gru(
|
||||
rearrange(x, 'b n d -> (b n) d'),
|
||||
rearrange(residual, 'b n d -> (b n) d')
|
||||
)
|
||||
|
||||
return gated_output.reshape_as(x)
|
||||
|
||||
|
||||
# feedforward
|
||||
|
||||
class GEGLU(nn.Module):
|
||||
def __init__(self, dim_in, dim_out):
|
||||
super().__init__()
|
||||
self.proj = nn.Linear(dim_in, dim_out * 2)
|
||||
|
||||
def forward(self, x):
|
||||
x, gate = self.proj(x).chunk(2, dim=-1)
|
||||
return x * F.gelu(gate)
|
||||
|
||||
|
||||
class FeedForward(nn.Module):
|
||||
def __init__(self, dim, dim_out=None, mult=4, glu=False, dropout=0.):
|
||||
super().__init__()
|
||||
inner_dim = int(dim * mult)
|
||||
dim_out = default(dim_out, dim)
|
||||
project_in = nn.Sequential(
|
||||
nn.Linear(dim, inner_dim),
|
||||
nn.GELU()
|
||||
) if not glu else GEGLU(dim, inner_dim)
|
||||
|
||||
self.net = nn.Sequential(
|
||||
project_in,
|
||||
nn.Dropout(dropout),
|
||||
nn.Linear(inner_dim, dim_out)
|
||||
)
|
||||
|
||||
def forward(self, x):
|
||||
return self.net(x)
|
||||
|
||||
|
||||
# attention.
|
||||
class Attention(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
dim,
|
||||
dim_head=DEFAULT_DIM_HEAD,
|
||||
heads=8,
|
||||
causal=False,
|
||||
mask=None,
|
||||
talking_heads=False,
|
||||
sparse_topk=None,
|
||||
use_entmax15=False,
|
||||
num_mem_kv=0,
|
||||
dropout=0.,
|
||||
on_attn=False
|
||||
):
|
||||
super().__init__()
|
||||
if use_entmax15:
|
||||
raise NotImplementedError("Check out entmax activation instead of softmax activation!")
|
||||
self.scale = dim_head ** -0.5
|
||||
self.heads = heads
|
||||
self.causal = causal
|
||||
self.mask = mask
|
||||
|
||||
inner_dim = dim_head * heads
|
||||
|
||||
self.to_q = nn.Linear(dim, inner_dim, bias=False)
|
||||
self.to_k = nn.Linear(dim, inner_dim, bias=False)
|
||||
self.to_v = nn.Linear(dim, inner_dim, bias=False)
|
||||
self.dropout = nn.Dropout(dropout)
|
||||
|
||||
# talking heads
|
||||
self.talking_heads = talking_heads
|
||||
if talking_heads:
|
||||
self.pre_softmax_proj = nn.Parameter(torch.randn(heads, heads))
|
||||
self.post_softmax_proj = nn.Parameter(torch.randn(heads, heads))
|
||||
|
||||
# explicit topk sparse attention
|
||||
self.sparse_topk = sparse_topk
|
||||
|
||||
# entmax
|
||||
#self.attn_fn = entmax15 if use_entmax15 else F.softmax
|
||||
self.attn_fn = F.softmax
|
||||
|
||||
# add memory key / values
|
||||
self.num_mem_kv = num_mem_kv
|
||||
if num_mem_kv > 0:
|
||||
self.mem_k = nn.Parameter(torch.randn(heads, num_mem_kv, dim_head))
|
||||
self.mem_v = nn.Parameter(torch.randn(heads, num_mem_kv, dim_head))
|
||||
|
||||
# attention on attention
|
||||
self.attn_on_attn = on_attn
|
||||
self.to_out = nn.Sequential(nn.Linear(inner_dim, dim * 2), nn.GLU()) if on_attn else nn.Linear(inner_dim, dim)
|
||||
|
||||
def forward(
|
||||
self,
|
||||
x,
|
||||
context=None,
|
||||
mask=None,
|
||||
context_mask=None,
|
||||
rel_pos=None,
|
||||
sinusoidal_emb=None,
|
||||
prev_attn=None,
|
||||
mem=None
|
||||
):
|
||||
b, n, _, h, talking_heads, device = *x.shape, self.heads, self.talking_heads, x.device
|
||||
kv_input = default(context, x)
|
||||
|
||||
q_input = x
|
||||
k_input = kv_input
|
||||
v_input = kv_input
|
||||
|
||||
if exists(mem):
|
||||
k_input = torch.cat((mem, k_input), dim=-2)
|
||||
v_input = torch.cat((mem, v_input), dim=-2)
|
||||
|
||||
if exists(sinusoidal_emb):
|
||||
# in shortformer, the query would start at a position offset depending on the past cached memory
|
||||
offset = k_input.shape[-2] - q_input.shape[-2]
|
||||
q_input = q_input + sinusoidal_emb(q_input, offset=offset)
|
||||
k_input = k_input + sinusoidal_emb(k_input)
|
||||
|
||||
q = self.to_q(q_input)
|
||||
k = self.to_k(k_input)
|
||||
v = self.to_v(v_input)
|
||||
|
||||
q, k, v = map(lambda t: rearrange(t, 'b n (h d) -> b h n d', h=h), (q, k, v))
|
||||
|
||||
input_mask = None
|
||||
if any(map(exists, (mask, context_mask))):
|
||||
q_mask = default(mask, lambda: torch.ones((b, n), device=device).bool())
|
||||
k_mask = q_mask if not exists(context) else context_mask
|
||||
k_mask = default(k_mask, lambda: torch.ones((b, k.shape[-2]), device=device).bool())
|
||||
q_mask = rearrange(q_mask, 'b i -> b () i ()')
|
||||
k_mask = rearrange(k_mask, 'b j -> b () () j')
|
||||
input_mask = q_mask * k_mask
|
||||
|
||||
if self.num_mem_kv > 0:
|
||||
mem_k, mem_v = map(lambda t: repeat(t, 'h n d -> b h n d', b=b), (self.mem_k, self.mem_v))
|
||||
k = torch.cat((mem_k, k), dim=-2)
|
||||
v = torch.cat((mem_v, v), dim=-2)
|
||||
if exists(input_mask):
|
||||
input_mask = F.pad(input_mask, (self.num_mem_kv, 0), value=True)
|
||||
|
||||
dots = einsum('b h i d, b h j d -> b h i j', q, k) * self.scale
|
||||
mask_value = max_neg_value(dots)
|
||||
|
||||
if exists(prev_attn):
|
||||
dots = dots + prev_attn
|
||||
|
||||
pre_softmax_attn = dots
|
||||
|
||||
if talking_heads:
|
||||
dots = einsum('b h i j, h k -> b k i j', dots, self.pre_softmax_proj).contiguous()
|
||||
|
||||
if exists(rel_pos):
|
||||
dots = rel_pos(dots)
|
||||
|
||||
if exists(input_mask):
|
||||
dots.masked_fill_(~input_mask, mask_value)
|
||||
del input_mask
|
||||
|
||||
if self.causal:
|
||||
i, j = dots.shape[-2:]
|
||||
r = torch.arange(i, device=device)
|
||||
mask = rearrange(r, 'i -> () () i ()') < rearrange(r, 'j -> () () () j')
|
||||
mask = F.pad(mask, (j - i, 0), value=False)
|
||||
dots.masked_fill_(mask, mask_value)
|
||||
del mask
|
||||
|
||||
if exists(self.sparse_topk) and self.sparse_topk < dots.shape[-1]:
|
||||
top, _ = dots.topk(self.sparse_topk, dim=-1)
|
||||
vk = top[..., -1].unsqueeze(-1).expand_as(dots)
|
||||
mask = dots < vk
|
||||
dots.masked_fill_(mask, mask_value)
|
||||
del mask
|
||||
|
||||
attn = self.attn_fn(dots, dim=-1)
|
||||
post_softmax_attn = attn
|
||||
|
||||
attn = self.dropout(attn)
|
||||
|
||||
if talking_heads:
|
||||
attn = einsum('b h i j, h k -> b k i j', attn, self.post_softmax_proj).contiguous()
|
||||
|
||||
out = einsum('b h i j, b h j d -> b h i d', attn, v)
|
||||
out = rearrange(out, 'b h n d -> b n (h d)')
|
||||
|
||||
intermediates = Intermediates(
|
||||
pre_softmax_attn=pre_softmax_attn,
|
||||
post_softmax_attn=post_softmax_attn
|
||||
)
|
||||
|
||||
return self.to_out(out), intermediates
|
||||
|
||||
|
||||
class AttentionLayers(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
dim,
|
||||
depth,
|
||||
heads=8,
|
||||
causal=False,
|
||||
cross_attend=False,
|
||||
only_cross=False,
|
||||
use_scalenorm=False,
|
||||
use_rmsnorm=False,
|
||||
use_rezero=False,
|
||||
rel_pos_num_buckets=32,
|
||||
rel_pos_max_distance=128,
|
||||
position_infused_attn=False,
|
||||
custom_layers=None,
|
||||
sandwich_coef=None,
|
||||
par_ratio=None,
|
||||
residual_attn=False,
|
||||
cross_residual_attn=False,
|
||||
macaron=False,
|
||||
pre_norm=True,
|
||||
gate_residual=False,
|
||||
**kwargs
|
||||
):
|
||||
super().__init__()
|
||||
ff_kwargs, kwargs = groupby_prefix_and_trim('ff_', kwargs)
|
||||
attn_kwargs, _ = groupby_prefix_and_trim('attn_', kwargs)
|
||||
|
||||
dim_head = attn_kwargs.get('dim_head', DEFAULT_DIM_HEAD)
|
||||
|
||||
self.dim = dim
|
||||
self.depth = depth
|
||||
self.layers = nn.ModuleList([])
|
||||
|
||||
self.has_pos_emb = position_infused_attn
|
||||
self.pia_pos_emb = FixedPositionalEmbedding(dim) if position_infused_attn else None
|
||||
self.rotary_pos_emb = always(None)
|
||||
|
||||
assert rel_pos_num_buckets <= rel_pos_max_distance, 'number of relative position buckets must be less than the relative position max distance'
|
||||
self.rel_pos = None
|
||||
|
||||
self.pre_norm = pre_norm
|
||||
|
||||
self.residual_attn = residual_attn
|
||||
self.cross_residual_attn = cross_residual_attn
|
||||
|
||||
norm_class = ScaleNorm if use_scalenorm else nn.LayerNorm
|
||||
norm_class = RMSNorm if use_rmsnorm else norm_class
|
||||
norm_fn = partial(norm_class, dim)
|
||||
|
||||
norm_fn = nn.Identity if use_rezero else norm_fn
|
||||
branch_fn = Rezero if use_rezero else None
|
||||
|
||||
if cross_attend and not only_cross:
|
||||
default_block = ('a', 'c', 'f')
|
||||
elif cross_attend and only_cross:
|
||||
default_block = ('c', 'f')
|
||||
else:
|
||||
default_block = ('a', 'f')
|
||||
|
||||
if macaron:
|
||||
default_block = ('f',) + default_block
|
||||
|
||||
if exists(custom_layers):
|
||||
layer_types = custom_layers
|
||||
elif exists(par_ratio):
|
||||
par_depth = depth * len(default_block)
|
||||
assert 1 < par_ratio <= par_depth, 'par ratio out of range'
|
||||
default_block = tuple(filter(not_equals('f'), default_block))
|
||||
par_attn = par_depth // par_ratio
|
||||
depth_cut = par_depth * 2 // 3 # 2 / 3 attention layer cutoff suggested by PAR paper
|
||||
par_width = (depth_cut + depth_cut // par_attn) // par_attn
|
||||
assert len(default_block) <= par_width, 'default block is too large for par_ratio'
|
||||
par_block = default_block + ('f',) * (par_width - len(default_block))
|
||||
par_head = par_block * par_attn
|
||||
layer_types = par_head + ('f',) * (par_depth - len(par_head))
|
||||
elif exists(sandwich_coef):
|
||||
assert sandwich_coef > 0 and sandwich_coef <= depth, 'sandwich coefficient should be less than the depth'
|
||||
layer_types = ('a',) * sandwich_coef + default_block * (depth - sandwich_coef) + ('f',) * sandwich_coef
|
||||
else:
|
||||
layer_types = default_block * depth
|
||||
|
||||
self.layer_types = layer_types
|
||||
self.num_attn_layers = len(list(filter(equals('a'), layer_types)))
|
||||
|
||||
for layer_type in self.layer_types:
|
||||
if layer_type == 'a':
|
||||
layer = Attention(dim, heads=heads, causal=causal, **attn_kwargs)
|
||||
elif layer_type == 'c':
|
||||
layer = Attention(dim, heads=heads, **attn_kwargs)
|
||||
elif layer_type == 'f':
|
||||
layer = FeedForward(dim, **ff_kwargs)
|
||||
layer = layer if not macaron else Scale(0.5, layer)
|
||||
else:
|
||||
raise Exception(f'invalid layer type {layer_type}')
|
||||
|
||||
if isinstance(layer, Attention) and exists(branch_fn):
|
||||
layer = branch_fn(layer)
|
||||
|
||||
if gate_residual:
|
||||
residual_fn = GRUGating(dim)
|
||||
else:
|
||||
residual_fn = Residual()
|
||||
|
||||
self.layers.append(nn.ModuleList([
|
||||
norm_fn(),
|
||||
layer,
|
||||
residual_fn
|
||||
]))
|
||||
|
||||
def forward(
|
||||
self,
|
||||
x,
|
||||
context=None,
|
||||
mask=None,
|
||||
context_mask=None,
|
||||
mems=None,
|
||||
return_hiddens=False
|
||||
):
|
||||
hiddens = []
|
||||
intermediates = []
|
||||
prev_attn = None
|
||||
prev_cross_attn = None
|
||||
|
||||
mems = mems.copy() if exists(mems) else [None] * self.num_attn_layers
|
||||
|
||||
for ind, (layer_type, (norm, block, residual_fn)) in enumerate(zip(self.layer_types, self.layers)):
|
||||
is_last = ind == (len(self.layers) - 1)
|
||||
|
||||
if layer_type == 'a':
|
||||
hiddens.append(x)
|
||||
layer_mem = mems.pop(0)
|
||||
|
||||
residual = x
|
||||
|
||||
if self.pre_norm:
|
||||
x = norm(x)
|
||||
|
||||
if layer_type == 'a':
|
||||
out, inter = block(x, mask=mask, sinusoidal_emb=self.pia_pos_emb, rel_pos=self.rel_pos,
|
||||
prev_attn=prev_attn, mem=layer_mem)
|
||||
elif layer_type == 'c':
|
||||
out, inter = block(x, context=context, mask=mask, context_mask=context_mask, prev_attn=prev_cross_attn)
|
||||
elif layer_type == 'f':
|
||||
out = block(x)
|
||||
|
||||
x = residual_fn(out, residual)
|
||||
|
||||
if layer_type in ('a', 'c'):
|
||||
intermediates.append(inter)
|
||||
|
||||
if layer_type == 'a' and self.residual_attn:
|
||||
prev_attn = inter.pre_softmax_attn
|
||||
elif layer_type == 'c' and self.cross_residual_attn:
|
||||
prev_cross_attn = inter.pre_softmax_attn
|
||||
|
||||
if not self.pre_norm and not is_last:
|
||||
x = norm(x)
|
||||
|
||||
if return_hiddens:
|
||||
intermediates = LayerIntermediates(
|
||||
hiddens=hiddens,
|
||||
attn_intermediates=intermediates
|
||||
)
|
||||
|
||||
return x, intermediates
|
||||
|
||||
return x
|
||||
|
||||
|
||||
class Encoder(AttentionLayers):
|
||||
def __init__(self, **kwargs):
|
||||
assert 'causal' not in kwargs, 'cannot set causality on encoder'
|
||||
super().__init__(causal=False, **kwargs)
|
||||
|
||||
|
||||
|
||||
class TransformerWrapper(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
*,
|
||||
num_tokens,
|
||||
max_seq_len,
|
||||
attn_layers,
|
||||
emb_dim=None,
|
||||
max_mem_len=0.,
|
||||
emb_dropout=0.,
|
||||
num_memory_tokens=None,
|
||||
tie_embedding=False,
|
||||
use_pos_emb=True
|
||||
):
|
||||
super().__init__()
|
||||
assert isinstance(attn_layers, AttentionLayers), 'attention layers must be one of Encoder or Decoder'
|
||||
|
||||
dim = attn_layers.dim
|
||||
emb_dim = default(emb_dim, dim)
|
||||
|
||||
self.max_seq_len = max_seq_len
|
||||
self.max_mem_len = max_mem_len
|
||||
self.num_tokens = num_tokens
|
||||
|
||||
self.token_emb = nn.Embedding(num_tokens, emb_dim)
|
||||
self.pos_emb = AbsolutePositionalEmbedding(emb_dim, max_seq_len) if (
|
||||
use_pos_emb and not attn_layers.has_pos_emb) else always(0)
|
||||
self.emb_dropout = nn.Dropout(emb_dropout)
|
||||
|
||||
self.project_emb = nn.Linear(emb_dim, dim) if emb_dim != dim else nn.Identity()
|
||||
self.attn_layers = attn_layers
|
||||
self.norm = nn.LayerNorm(dim)
|
||||
|
||||
self.init_()
|
||||
|
||||
self.to_logits = nn.Linear(dim, num_tokens) if not tie_embedding else lambda t: t @ self.token_emb.weight.t()
|
||||
|
||||
# memory tokens (like [cls]) from Memory Transformers paper
|
||||
num_memory_tokens = default(num_memory_tokens, 0)
|
||||
self.num_memory_tokens = num_memory_tokens
|
||||
if num_memory_tokens > 0:
|
||||
self.memory_tokens = nn.Parameter(torch.randn(num_memory_tokens, dim))
|
||||
|
||||
# let funnel encoder know number of memory tokens, if specified
|
||||
if hasattr(attn_layers, 'num_memory_tokens'):
|
||||
attn_layers.num_memory_tokens = num_memory_tokens
|
||||
|
||||
def init_(self):
|
||||
nn.init.normal_(self.token_emb.weight, std=0.02)
|
||||
|
||||
def forward(
|
||||
self,
|
||||
x,
|
||||
return_embeddings=False,
|
||||
mask=None,
|
||||
return_mems=False,
|
||||
return_attn=False,
|
||||
mems=None,
|
||||
**kwargs
|
||||
):
|
||||
b, n, device, num_mem = *x.shape, x.device, self.num_memory_tokens
|
||||
x = self.token_emb(x)
|
||||
x += self.pos_emb(x)
|
||||
x = self.emb_dropout(x)
|
||||
|
||||
x = self.project_emb(x)
|
||||
|
||||
if num_mem > 0:
|
||||
mem = repeat(self.memory_tokens, 'n d -> b n d', b=b)
|
||||
x = torch.cat((mem, x), dim=1)
|
||||
|
||||
# auto-handle masking after appending memory tokens
|
||||
if exists(mask):
|
||||
mask = F.pad(mask, (num_mem, 0), value=True)
|
||||
|
||||
x, intermediates = self.attn_layers(x, mask=mask, mems=mems, return_hiddens=True, **kwargs)
|
||||
x = self.norm(x)
|
||||
|
||||
mem, x = x[:, :num_mem], x[:, num_mem:]
|
||||
|
||||
out = self.to_logits(x) if not return_embeddings else x
|
||||
|
||||
if return_mems:
|
||||
hiddens = intermediates.hiddens
|
||||
new_mems = list(map(lambda pair: torch.cat(pair, dim=-2), zip(mems, hiddens))) if exists(mems) else hiddens
|
||||
new_mems = list(map(lambda t: t[..., -self.max_mem_len:, :].detach(), new_mems))
|
||||
return out, new_mems
|
||||
|
||||
if return_attn:
|
||||
attn_maps = list(map(lambda t: t.post_softmax_attn, intermediates.attn_intermediates))
|
||||
return out, attn_maps
|
||||
|
||||
return out
|
||||
@@ -0,0 +1,129 @@
|
||||
import os
|
||||
from omegaconf import OmegaConf
|
||||
import torch
|
||||
import torchvision
|
||||
from .scripts.evaluation.funcs import load_model_checkpoint, batch_ddim_sampling, get_latent_z
|
||||
from .utils.utils import instantiate_from_config
|
||||
from einops import repeat
|
||||
import folder_paths
|
||||
import comfy.model_management as mm
|
||||
import comfy.utils
|
||||
from contextlib import nullcontext
|
||||
|
||||
try:
|
||||
import xformers
|
||||
import xformers.ops
|
||||
|
||||
XFORMERS_IS_AVAILABLE = True
|
||||
except:
|
||||
XFORMERS_IS_AVAILABLE = False
|
||||
|
||||
def convert_dtype(dtype_str):
|
||||
if dtype_str == 'fp32':
|
||||
return torch.float32
|
||||
elif dtype_str == 'fp16':
|
||||
return torch.float16
|
||||
elif dtype_str == 'bf16':
|
||||
return torch.bfloat16
|
||||
else:
|
||||
raise NotImplementedError
|
||||
|
||||
script_directory = os.path.dirname(os.path.abspath(__file__))
|
||||
class DynamiCrafterI2V:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {"required": {
|
||||
"ckpt_name": (folder_paths.get_filename_list("checkpoints"), ),
|
||||
"image": ("IMAGE",),
|
||||
"steps": ("INT", {"default": 50, "min": 1, "max": 200, "step": 1}),
|
||||
"cfg": ("FLOAT", {"default": 7.0, "min": 0.0, "max": 20.0, "step": 0.01}),
|
||||
"eta": ("FLOAT", {"default": 1.0, "min": 0.0, "max": 20.0, "step": 0.01}),
|
||||
"prompt": ("STRING", {"multiline": True, "default": "",}),
|
||||
"seed": ("INT", {"default": 0, "min": 0, "max": 0xffffffffffffffff}),
|
||||
"fs": ("INT", {"default": 3, "min": 0, "max": 10, "step": 1}),
|
||||
"dtype": (
|
||||
[
|
||||
'bf16',
|
||||
'fp32',
|
||||
'fp16',
|
||||
], {
|
||||
"default": 'auto'
|
||||
}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES = ("image",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "DynamiCrafter"
|
||||
|
||||
def process(self, image, dtype, ckpt_name, prompt, cfg, steps, eta, seed, fs):
|
||||
device = mm.get_torch_device()
|
||||
mm.unload_all_models()
|
||||
|
||||
torch.manual_seed(seed)
|
||||
custom_config = {
|
||||
'dtype': dtype,
|
||||
'ckpt_name': ckpt_name,
|
||||
}
|
||||
dtype = convert_dtype(dtype)
|
||||
if not hasattr(self, 'model') or self.model == None or custom_config != self.current_config:
|
||||
self.current_config = custom_config
|
||||
model_path = folder_paths.get_full_path("checkpoints", ckpt_name)
|
||||
base_name, _ = os.path.splitext(ckpt_name)
|
||||
config_file=os.path.join(script_directory, "configs", f"{base_name}.yaml")
|
||||
config = OmegaConf.load(config_file)
|
||||
model_config = config.pop("model", OmegaConf.create())
|
||||
model_config['params']['unet_config']['params']['use_checkpoint']=False
|
||||
self.model = instantiate_from_config(model_config)
|
||||
self.model = load_model_checkpoint(self.model, model_path)
|
||||
self.model.eval().to(dtype).to(device)
|
||||
|
||||
channels = self.model.model.diffusion_model.out_channels
|
||||
frames = self.model.temporal_length
|
||||
B, H, W, C = image.shape
|
||||
|
||||
noise_shape = [B, channels, frames, H // 8, W // 8]
|
||||
|
||||
image = image * 2 - 1
|
||||
image = image.permute(0, 3, 1, 2).to(dtype).to(device)
|
||||
autocast_condition = (dtype != torch.float32) and not comfy.model_management.is_device_mps(device)
|
||||
with torch.autocast(comfy.model_management.get_autocast_device(device), dtype=dtype) if autocast_condition else nullcontext():
|
||||
text_emb = self.model.get_learned_conditioning([prompt])
|
||||
|
||||
z = get_latent_z(self.model, image.unsqueeze(2)) #bc,1,hw
|
||||
image
|
||||
img_tensor_repeat = repeat(z, 'b c t h w -> b c (repeat t) h w', repeat=frames)
|
||||
cond_images = self.model.embedder(image)
|
||||
img_emb = self.model.image_proj_model(cond_images)
|
||||
imtext_cond = torch.cat([text_emb, img_emb], dim=1)
|
||||
fs = torch.tensor([fs], dtype=torch.long, device=self.model.device)
|
||||
cond = {"c_crossattn": [imtext_cond], "fs": fs, "c_concat": [img_tensor_repeat]}
|
||||
## inference
|
||||
batch_samples = batch_ddim_sampling(self.model, cond, noise_shape, n_samples=1, ddim_steps=steps, ddim_eta=eta, cfg_scale=cfg)
|
||||
## b,samples,c,t,h,w
|
||||
prompt_str = prompt.replace("/", "_slash_") if "/" in prompt else prompt
|
||||
prompt_str = prompt_str.replace(" ", "_") if " " in prompt else prompt_str
|
||||
prompt_str=prompt_str[:40]
|
||||
if len(prompt_str) == 0:
|
||||
prompt_str = 'empty_prompt'
|
||||
|
||||
n_samples = batch_samples.shape[1]
|
||||
for idx, vid_tensor in enumerate(batch_samples):
|
||||
video = vid_tensor.detach().cpu()
|
||||
video = torch.clamp(video.float(), -1., 1.)
|
||||
video = video.permute(2, 0, 1, 3, 4) # t,n,c,h,w
|
||||
frame_grids = [torchvision.utils.make_grid(framesheet, nrow=int(n_samples)) for framesheet in video] #[3, 1*h, n*w]
|
||||
grid = torch.stack(frame_grids, dim=0) # stack in temporal dim [t, 3, n*h, w]
|
||||
grid = (grid + 1.0) / 2.0
|
||||
grid = grid.permute(0, 2, 3, 1)
|
||||
|
||||
return (grid,)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"DynamiCrafterI2V": DynamiCrafterI2V,
|
||||
}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"DynamiCrafterI2V": "DynamiCrafterI2V",
|
||||
}
|
||||

|
After Width: | Height: | Size: 744 KiB |

|
After Width: | Height: | Size: 976 KiB |

|
After Width: | Height: | Size: 451 KiB |

|
After Width: | Height: | Size: 1.0 MiB |

|
After Width: | Height: | Size: 694 KiB |

|
After Width: | Height: | Size: 682 KiB |

|
After Width: | Height: | Size: 901 KiB |
@@ -0,0 +1,8 @@
|
||||
a man in an astronaut suit playing a guitar
|
||||
riding a bike under a bridge
|
||||
time-lapse of a blooming flower with leaves and a stem
|
||||
fireworks display
|
||||
a beautiful woman with long hair and a dress blowing in the wind
|
||||
pouring beer into a glass of ice and beer
|
||||
a robot is walking through a destroyed city
|
||||
a group of penguins walking on a beach
|
||||

|
After Width: | Height: | Size: 599 KiB |

|
After Width: | Height: | Size: 329 KiB |

|
After Width: | Height: | Size: 422 KiB |

|
After Width: | Height: | Size: 94 KiB |

|
After Width: | Height: | Size: 49 KiB |

|
After Width: | Height: | Size: 232 KiB |

|
After Width: | Height: | Size: 132 KiB |

|
After Width: | Height: | Size: 139 KiB |

|
After Width: | Height: | Size: 202 KiB |
@@ -0,0 +1,8 @@
|
||||
man fishing in a boat at sunset
|
||||
a brown bear is walking in a zoo enclosure, some rocks around
|
||||
boy walking on the street
|
||||
two people dancing
|
||||
a campfire on the beach and the ocean waves in the background
|
||||
girl with fires and smoke on his head
|
||||
girl talking and blinking
|
||||
bear playing guitar happily, snowing
|
||||

|
After Width: | Height: | Size: 167 KiB |

|
After Width: | Height: | Size: 238 KiB |

|
After Width: | Height: | Size: 190 KiB |

|
After Width: | Height: | Size: 253 KiB |

|
After Width: | Height: | Size: 200 KiB |

|
After Width: | Height: | Size: 230 KiB |
@@ -0,0 +1,8 @@
|
||||
time-lapse of a blooming flower with leaves and a stem
|
||||
a bonfire is lit in the middle of a field
|
||||
a woman looking out in the rain
|
||||
rotating view, small house
|
||||
pouring honey onto some slices of bread
|
||||
a sailboat sailing in rough seas with a dramatic sunset
|
||||
a boat traveling on the ocean
|
||||
a group of penguins walking on a beach
|
||||

|
After Width: | Height: | Size: 239 KiB |

|
After Width: | Height: | Size: 215 KiB |

|
After Width: | Height: | Size: 75 KiB |

|
After Width: | Height: | Size: 79 KiB |

|
After Width: | Height: | Size: 366 KiB |

|
After Width: | Height: | Size: 363 KiB |
@@ -0,0 +1,3 @@
|
||||
a smiling girl
|
||||
rotating view
|
||||
a man is walking towards a tree
|
||||

|
After Width: | Height: | Size: 215 KiB |

|
After Width: | Height: | Size: 231 KiB |

|
After Width: | Height: | Size: 1.0 MiB |

|
After Width: | Height: | Size: 308 KiB |

|
After Width: | Height: | Size: 348 KiB |
@@ -0,0 +1,3 @@
|
||||
a beach with waves and clouds at sunset
|
||||
clothes swaying in the wind
|
||||
flowers swaying in the wind
|
||||
@@ -0,0 +1,16 @@
|
||||
decord>=0.6.0
|
||||
einops>=0.3.0
|
||||
imageio>=2.9.0
|
||||
numpy>=1.24.2
|
||||
omegaconf>=2.1.1
|
||||
opencv_python
|
||||
pandas>=2.0.0
|
||||
Pillow>=9.5.0
|
||||
pytorch_lightning>=1.8.3
|
||||
PyYAML>=6.0
|
||||
tqdm>=4.65.0
|
||||
transformers>=4.25.1
|
||||
timm
|
||||
scikit-learn
|
||||
open_clip_torch==2.12.0
|
||||
kornia
|
||||
@@ -0,0 +1,47 @@
|
||||
import datetime
|
||||
import argparse, importlib
|
||||
from pytorch_lightning import seed_everything
|
||||
|
||||
import torch
|
||||
import torch.distributed as dist
|
||||
|
||||
def setup_dist(local_rank):
|
||||
if dist.is_initialized():
|
||||
return
|
||||
torch.cuda.set_device(local_rank)
|
||||
torch.distributed.init_process_group('nccl', init_method='env://')
|
||||
|
||||
|
||||
def get_dist_info():
|
||||
if dist.is_available():
|
||||
initialized = dist.is_initialized()
|
||||
else:
|
||||
initialized = False
|
||||
if initialized:
|
||||
rank = dist.get_rank()
|
||||
world_size = dist.get_world_size()
|
||||
else:
|
||||
rank = 0
|
||||
world_size = 1
|
||||
return rank, world_size
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
now = datetime.datetime.now().strftime("%Y-%m-%d-%H-%M-%S")
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--module", type=str, help="module name", default="inference")
|
||||
parser.add_argument("--local_rank", type=int, nargs="?", help="for ddp", default=0)
|
||||
args, unknown = parser.parse_known_args()
|
||||
inference_api = importlib.import_module(args.module, package=None)
|
||||
|
||||
inference_parser = inference_api.get_parser()
|
||||
inference_args, unknown = inference_parser.parse_known_args()
|
||||
|
||||
seed_everything(inference_args.seed)
|
||||
setup_dist(args.local_rank)
|
||||
torch.backends.cudnn.benchmark = True
|
||||
rank, gpu_num = get_dist_info()
|
||||
|
||||
# inference_args.savedir = inference_args.savedir+str('_seed')+str(inference_args.seed)
|
||||
print("@DynamiCrafter Inference [rank%d]: %s"%(rank, now))
|
||||
inference_api.run_inference(inference_args, gpu_num, rank)
|
||||
@@ -0,0 +1,226 @@
|
||||
import os, sys, glob
|
||||
import numpy as np
|
||||
from collections import OrderedDict
|
||||
from decord import VideoReader, cpu
|
||||
import cv2
|
||||
|
||||
import torch
|
||||
import torchvision
|
||||
sys.path.insert(1, os.path.join(sys.path[0], '..', '..'))
|
||||
from ...lvdm.models.samplers.ddim import DDIMSampler
|
||||
from einops import rearrange
|
||||
|
||||
|
||||
def batch_ddim_sampling(model, cond, noise_shape, n_samples=1, ddim_steps=50, ddim_eta=1.0,\
|
||||
cfg_scale=1.0, temporal_cfg_scale=None, **kwargs):
|
||||
ddim_sampler = DDIMSampler(model)
|
||||
uncond_type = model.uncond_type
|
||||
batch_size = noise_shape[0]
|
||||
fs = cond["fs"]
|
||||
del cond["fs"]
|
||||
if noise_shape[-1] == 32:
|
||||
timestep_spacing = "uniform"
|
||||
guidance_rescale = 0.0
|
||||
else:
|
||||
timestep_spacing = "uniform_trailing"
|
||||
guidance_rescale = 0.7
|
||||
## construct unconditional guidance
|
||||
if cfg_scale != 1.0:
|
||||
if uncond_type == "empty_seq":
|
||||
prompts = batch_size * [""]
|
||||
#prompts = N * T * [""] ## if is_imgbatch=True
|
||||
uc_emb = model.get_learned_conditioning(prompts)
|
||||
elif uncond_type == "zero_embed":
|
||||
c_emb = cond["c_crossattn"][0] if isinstance(cond, dict) else cond
|
||||
uc_emb = torch.zeros_like(c_emb)
|
||||
|
||||
## process image embedding token
|
||||
if hasattr(model, 'embedder'):
|
||||
uc_img = torch.zeros(noise_shape[0],3,224,224).to(model.device)
|
||||
## img: b c h w >> b l c
|
||||
uc_img = model.embedder(uc_img)
|
||||
uc_img = model.image_proj_model(uc_img)
|
||||
uc_emb = torch.cat([uc_emb, uc_img], dim=1)
|
||||
|
||||
if isinstance(cond, dict):
|
||||
uc = {key:cond[key] for key in cond.keys()}
|
||||
uc.update({'c_crossattn': [uc_emb]})
|
||||
else:
|
||||
uc = uc_emb
|
||||
else:
|
||||
uc = None
|
||||
|
||||
x_T = None
|
||||
batch_variants = []
|
||||
|
||||
for _ in range(n_samples):
|
||||
if ddim_sampler is not None:
|
||||
kwargs.update({"clean_cond": True})
|
||||
samples, _ = ddim_sampler.sample(S=ddim_steps,
|
||||
conditioning=cond,
|
||||
batch_size=noise_shape[0],
|
||||
shape=noise_shape[1:],
|
||||
verbose=False,
|
||||
unconditional_guidance_scale=cfg_scale,
|
||||
unconditional_conditioning=uc,
|
||||
eta=ddim_eta,
|
||||
temporal_length=noise_shape[2],
|
||||
conditional_guidance_scale_temporal=temporal_cfg_scale,
|
||||
x_T=x_T,
|
||||
fs=fs,
|
||||
timestep_spacing=timestep_spacing,
|
||||
guidance_rescale=guidance_rescale,
|
||||
**kwargs
|
||||
)
|
||||
## reconstruct from latent to pixel space
|
||||
batch_images = model.decode_first_stage(samples)
|
||||
batch_variants.append(batch_images)
|
||||
## batch, <samples>, c, t, h, w
|
||||
batch_variants = torch.stack(batch_variants, dim=1)
|
||||
return batch_variants
|
||||
|
||||
|
||||
def get_filelist(data_dir, ext='*'):
|
||||
file_list = glob.glob(os.path.join(data_dir, '*.%s'%ext))
|
||||
file_list.sort()
|
||||
return file_list
|
||||
|
||||
def get_dirlist(path):
|
||||
list = []
|
||||
if (os.path.exists(path)):
|
||||
files = os.listdir(path)
|
||||
for file in files:
|
||||
m = os.path.join(path,file)
|
||||
if (os.path.isdir(m)):
|
||||
list.append(m)
|
||||
list.sort()
|
||||
return list
|
||||
|
||||
|
||||
def load_model_checkpoint(model, ckpt):
|
||||
def load_checkpoint(model, ckpt, full_strict):
|
||||
state_dict = torch.load(ckpt, map_location="cpu")
|
||||
if "state_dict" in list(state_dict.keys()):
|
||||
state_dict = state_dict["state_dict"]
|
||||
try:
|
||||
model.load_state_dict(state_dict, strict=full_strict)
|
||||
except:
|
||||
## rename the keys for 256x256 model
|
||||
new_pl_sd = OrderedDict()
|
||||
for k,v in state_dict.items():
|
||||
new_pl_sd[k] = v
|
||||
|
||||
for k in list(new_pl_sd.keys()):
|
||||
if "framestride_embed" in k:
|
||||
new_key = k.replace("framestride_embed", "fps_embedding")
|
||||
new_pl_sd[new_key] = new_pl_sd[k]
|
||||
del new_pl_sd[k]
|
||||
model.load_state_dict(new_pl_sd, strict=full_strict)
|
||||
else:
|
||||
## deepspeed
|
||||
new_pl_sd = OrderedDict()
|
||||
for key in state_dict['module'].keys():
|
||||
new_pl_sd[key[16:]]=state_dict['module'][key]
|
||||
model.load_state_dict(new_pl_sd, strict=full_strict)
|
||||
|
||||
return model
|
||||
load_checkpoint(model, ckpt, full_strict=True)
|
||||
print('>>> model checkpoint loaded.')
|
||||
return model
|
||||
|
||||
|
||||
def load_prompts(prompt_file):
|
||||
f = open(prompt_file, 'r')
|
||||
prompt_list = []
|
||||
for idx, line in enumerate(f.readlines()):
|
||||
l = line.strip()
|
||||
if len(l) != 0:
|
||||
prompt_list.append(l)
|
||||
f.close()
|
||||
return prompt_list
|
||||
|
||||
|
||||
def load_video_batch(filepath_list, frame_stride, video_size=(256,256), video_frames=16):
|
||||
'''
|
||||
Notice about some special cases:
|
||||
1. video_frames=-1 means to take all the frames (with fs=1)
|
||||
2. when the total video frames is less than required, padding strategy will be used (repreated last frame)
|
||||
'''
|
||||
fps_list = []
|
||||
batch_tensor = []
|
||||
assert frame_stride > 0, "valid frame stride should be a positive interge!"
|
||||
for filepath in filepath_list:
|
||||
padding_num = 0
|
||||
vidreader = VideoReader(filepath, ctx=cpu(0), width=video_size[1], height=video_size[0])
|
||||
fps = vidreader.get_avg_fps()
|
||||
total_frames = len(vidreader)
|
||||
max_valid_frames = (total_frames-1) // frame_stride + 1
|
||||
if video_frames < 0:
|
||||
## all frames are collected: fs=1 is a must
|
||||
required_frames = total_frames
|
||||
frame_stride = 1
|
||||
else:
|
||||
required_frames = video_frames
|
||||
query_frames = min(required_frames, max_valid_frames)
|
||||
frame_indices = [frame_stride*i for i in range(query_frames)]
|
||||
|
||||
## [t,h,w,c] -> [c,t,h,w]
|
||||
frames = vidreader.get_batch(frame_indices)
|
||||
frame_tensor = torch.tensor(frames.asnumpy()).permute(3, 0, 1, 2).float()
|
||||
frame_tensor = (frame_tensor / 255. - 0.5) * 2
|
||||
if max_valid_frames < required_frames:
|
||||
padding_num = required_frames - max_valid_frames
|
||||
frame_tensor = torch.cat([frame_tensor, *([frame_tensor[:,-1:,:,:]]*padding_num)], dim=1)
|
||||
print(f'{os.path.split(filepath)[1]} is not long enough: {padding_num} frames padded.')
|
||||
batch_tensor.append(frame_tensor)
|
||||
sample_fps = int(fps/frame_stride)
|
||||
fps_list.append(sample_fps)
|
||||
|
||||
return torch.stack(batch_tensor, dim=0)
|
||||
|
||||
from PIL import Image
|
||||
def load_image_batch(filepath_list, image_size=(256,256)):
|
||||
batch_tensor = []
|
||||
for filepath in filepath_list:
|
||||
_, filename = os.path.split(filepath)
|
||||
_, ext = os.path.splitext(filename)
|
||||
if ext == '.mp4':
|
||||
vidreader = VideoReader(filepath, ctx=cpu(0), width=image_size[1], height=image_size[0])
|
||||
frame = vidreader.get_batch([0])
|
||||
img_tensor = torch.tensor(frame.asnumpy()).squeeze(0).permute(2, 0, 1).float()
|
||||
elif ext == '.png' or ext == '.jpg':
|
||||
img = Image.open(filepath).convert("RGB")
|
||||
rgb_img = np.array(img, np.float32)
|
||||
#bgr_img = cv2.imread(filepath, cv2.IMREAD_COLOR)
|
||||
#bgr_img = cv2.cvtColor(bgr_img, cv2.COLOR_BGR2RGB)
|
||||
rgb_img = cv2.resize(rgb_img, (image_size[1],image_size[0]), interpolation=cv2.INTER_LINEAR)
|
||||
img_tensor = torch.from_numpy(rgb_img).permute(2, 0, 1).float()
|
||||
else:
|
||||
print(f'ERROR: <{ext}> image loading only support format: [mp4], [png], [jpg]')
|
||||
raise NotImplementedError
|
||||
img_tensor = (img_tensor / 255. - 0.5) * 2
|
||||
batch_tensor.append(img_tensor)
|
||||
return torch.stack(batch_tensor, dim=0)
|
||||
|
||||
|
||||
def save_videos(batch_tensors, savedir, filenames, fps=10):
|
||||
# b,samples,c,t,h,w
|
||||
n_samples = batch_tensors.shape[1]
|
||||
for idx, vid_tensor in enumerate(batch_tensors):
|
||||
video = vid_tensor.detach().cpu()
|
||||
video = torch.clamp(video.float(), -1., 1.)
|
||||
video = video.permute(2, 0, 1, 3, 4) # t,n,c,h,w
|
||||
frame_grids = [torchvision.utils.make_grid(framesheet, nrow=int(n_samples)) for framesheet in video] #[3, 1*h, n*w]
|
||||
grid = torch.stack(frame_grids, dim=0) # stack in temporal dim [t, 3, n*h, w]
|
||||
grid = (grid + 1.0) / 2.0
|
||||
grid = (grid * 255).to(torch.uint8).permute(0, 2, 3, 1)
|
||||
savepath = os.path.join(savedir, f"{filenames[idx]}.mp4")
|
||||
torchvision.io.write_video(savepath, grid, fps=fps, video_codec='h264', options={'crf': '10'})
|
||||
|
||||
|
||||
def get_latent_z(model, videos):
|
||||
b, c, t, h, w = videos.shape
|
||||
x = rearrange(videos, 'b c t h w -> (b t) c h w')
|
||||
z = model.encode_first_stage(x)
|
||||
z = rearrange(z, '(b t) c h w -> b c t h w', b=b, t=t)
|
||||
return z
|
||||
@@ -0,0 +1,357 @@
|
||||
import argparse, os, sys, glob
|
||||
import datetime, time
|
||||
from omegaconf import OmegaConf
|
||||
from tqdm import tqdm
|
||||
from einops import rearrange, repeat
|
||||
from collections import OrderedDict
|
||||
|
||||
import torch
|
||||
import torchvision
|
||||
import torchvision.transforms as transforms
|
||||
from pytorch_lightning import seed_everything
|
||||
from PIL import Image
|
||||
sys.path.insert(1, os.path.join(sys.path[0], '..', '..'))
|
||||
from ...lvdm.models.samplers.ddim import DDIMSampler
|
||||
from ...lvdm.models.samplers.ddim_multiplecond import DDIMSampler as DDIMSampler_multicond
|
||||
from ...utils.utils import instantiate_from_config
|
||||
|
||||
|
||||
def get_filelist(data_dir, postfixes):
|
||||
patterns = [os.path.join(data_dir, f"*.{postfix}") for postfix in postfixes]
|
||||
file_list = []
|
||||
for pattern in patterns:
|
||||
file_list.extend(glob.glob(pattern))
|
||||
file_list.sort()
|
||||
return file_list
|
||||
|
||||
def load_model_checkpoint(model, ckpt):
|
||||
state_dict = torch.load(ckpt, map_location="cpu")
|
||||
if "state_dict" in list(state_dict.keys()):
|
||||
state_dict = state_dict["state_dict"]
|
||||
try:
|
||||
model.load_state_dict(state_dict, strict=True)
|
||||
except:
|
||||
## rename the keys for 256x256 model
|
||||
new_pl_sd = OrderedDict()
|
||||
for k,v in state_dict.items():
|
||||
new_pl_sd[k] = v
|
||||
|
||||
for k in list(new_pl_sd.keys()):
|
||||
if "framestride_embed" in k:
|
||||
new_key = k.replace("framestride_embed", "fps_embedding")
|
||||
new_pl_sd[new_key] = new_pl_sd[k]
|
||||
del new_pl_sd[k]
|
||||
model.load_state_dict(new_pl_sd, strict=True)
|
||||
else:
|
||||
# deepspeed
|
||||
new_pl_sd = OrderedDict()
|
||||
for key in state_dict['module'].keys():
|
||||
new_pl_sd[key[16:]]=state_dict['module'][key]
|
||||
model.load_state_dict(new_pl_sd)
|
||||
print('>>> model checkpoint loaded.')
|
||||
return model
|
||||
|
||||
def load_prompts(prompt_file):
|
||||
f = open(prompt_file, 'r')
|
||||
prompt_list = []
|
||||
for idx, line in enumerate(f.readlines()):
|
||||
l = line.strip()
|
||||
if len(l) != 0:
|
||||
prompt_list.append(l)
|
||||
f.close()
|
||||
return prompt_list
|
||||
|
||||
def load_data_prompts(data_dir, video_size=(256,256), video_frames=16, interp=False):
|
||||
transform = transforms.Compose([
|
||||
transforms.Resize(min(video_size)),
|
||||
transforms.CenterCrop(video_size),
|
||||
transforms.ToTensor(),
|
||||
transforms.Normalize(mean=(0.5, 0.5, 0.5), std=(0.5, 0.5, 0.5))])
|
||||
## load prompts
|
||||
prompt_file = get_filelist(data_dir, ['txt'])
|
||||
assert len(prompt_file) > 0, "Error: found NO prompt file!"
|
||||
###### default prompt
|
||||
default_idx = 0
|
||||
default_idx = min(default_idx, len(prompt_file)-1)
|
||||
if len(prompt_file) > 1:
|
||||
print(f"Warning: multiple prompt files exist. The one {os.path.split(prompt_file[default_idx])[1]} is used.")
|
||||
## only use the first one (sorted by name) if multiple exist
|
||||
|
||||
## load video
|
||||
file_list = get_filelist(data_dir, ['jpg', 'png', 'jpeg', 'JPEG', 'PNG'])
|
||||
# assert len(file_list) == n_samples, "Error: data and prompts are NOT paired!"
|
||||
data_list = []
|
||||
filename_list = []
|
||||
prompt_list = load_prompts(prompt_file[default_idx])
|
||||
n_samples = len(prompt_list)
|
||||
for idx in range(n_samples):
|
||||
if interp:
|
||||
image1 = Image.open(file_list[2*idx]).convert('RGB')
|
||||
image_tensor1 = transform(image1).unsqueeze(1) # [c,1,h,w]
|
||||
image2 = Image.open(file_list[2*idx+1]).convert('RGB')
|
||||
image_tensor2 = transform(image2).unsqueeze(1) # [c,1,h,w]
|
||||
frame_tensor1 = repeat(image_tensor1, 'c t h w -> c (repeat t) h w', repeat=video_frames//2)
|
||||
frame_tensor2 = repeat(image_tensor2, 'c t h w -> c (repeat t) h w', repeat=video_frames//2)
|
||||
frame_tensor = torch.cat([frame_tensor1, frame_tensor2], dim=1)
|
||||
_, filename = os.path.split(file_list[idx*2])
|
||||
else:
|
||||
image = Image.open(file_list[idx]).convert('RGB')
|
||||
image_tensor = transform(image).unsqueeze(1) # [c,1,h,w]
|
||||
frame_tensor = repeat(image_tensor, 'c t h w -> c (repeat t) h w', repeat=video_frames)
|
||||
_, filename = os.path.split(file_list[idx])
|
||||
|
||||
data_list.append(frame_tensor)
|
||||
filename_list.append(filename)
|
||||
|
||||
return filename_list, data_list, prompt_list
|
||||
|
||||
|
||||
def save_results(prompt, samples, filename, fakedir, fps=8, loop=False):
|
||||
filename = filename.split('.')[0]+'.mp4'
|
||||
prompt = prompt[0] if isinstance(prompt, list) else prompt
|
||||
|
||||
## save video
|
||||
videos = [samples]
|
||||
savedirs = [fakedir]
|
||||
for idx, video in enumerate(videos):
|
||||
if video is None:
|
||||
continue
|
||||
# b,c,t,h,w
|
||||
video = video.detach().cpu()
|
||||
video = torch.clamp(video.float(), -1., 1.)
|
||||
n = video.shape[0]
|
||||
video = video.permute(2, 0, 1, 3, 4) # t,n,c,h,w
|
||||
if loop:
|
||||
video = video[:-1,...]
|
||||
|
||||
frame_grids = [torchvision.utils.make_grid(framesheet, nrow=int(n), padding=0) for framesheet in video] #[3, 1*h, n*w]
|
||||
grid = torch.stack(frame_grids, dim=0) # stack in temporal dim [t, 3, h, n*w]
|
||||
grid = (grid + 1.0) / 2.0
|
||||
grid = (grid * 255).to(torch.uint8).permute(0, 2, 3, 1)
|
||||
path = os.path.join(savedirs[idx], filename)
|
||||
torchvision.io.write_video(path, grid, fps=fps, video_codec='h264', options={'crf': '10'}) ## crf indicates the quality
|
||||
|
||||
|
||||
def save_results_seperate(prompt, samples, filename, fakedir, fps=10, loop=False):
|
||||
prompt = prompt[0] if isinstance(prompt, list) else prompt
|
||||
|
||||
## save video
|
||||
videos = [samples]
|
||||
savedirs = [fakedir]
|
||||
for idx, video in enumerate(videos):
|
||||
if video is None:
|
||||
continue
|
||||
# b,c,t,h,w
|
||||
video = video.detach().cpu()
|
||||
if loop: # remove the last frame
|
||||
video = video[:,:,:-1,...]
|
||||
video = torch.clamp(video.float(), -1., 1.)
|
||||
n = video.shape[0]
|
||||
for i in range(n):
|
||||
grid = video[i,...]
|
||||
grid = (grid + 1.0) / 2.0
|
||||
grid = (grid * 255).to(torch.uint8).permute(1, 2, 3, 0) #thwc
|
||||
path = os.path.join(savedirs[idx].replace('samples', 'samples_separate'), f'{filename.split(".")[0]}_sample{i}.mp4')
|
||||
torchvision.io.write_video(path, grid, fps=fps, video_codec='h264', options={'crf': '10'})
|
||||
|
||||
def get_latent_z(model, videos):
|
||||
b, c, t, h, w = videos.shape
|
||||
x = rearrange(videos, 'b c t h w -> (b t) c h w')
|
||||
z = model.encode_first_stage(x)
|
||||
z = rearrange(z, '(b t) c h w -> b c t h w', b=b, t=t)
|
||||
return z
|
||||
|
||||
|
||||
def image_guided_synthesis(model, prompts, videos, noise_shape, n_samples=1, ddim_steps=50, ddim_eta=1., \
|
||||
unconditional_guidance_scale=1.0, cfg_img=None, fs=None, text_input=False, multiple_cond_cfg=False, loop=False, interp=False, timestep_spacing='uniform', guidance_rescale=0.0, **kwargs):
|
||||
ddim_sampler = DDIMSampler(model) if not multiple_cond_cfg else DDIMSampler_multicond(model)
|
||||
batch_size = noise_shape[0]
|
||||
fs = torch.tensor([fs] * batch_size, dtype=torch.long, device=model.device)
|
||||
|
||||
if not text_input:
|
||||
prompts = [""]*batch_size
|
||||
|
||||
img = videos[:,:,0] #bchw
|
||||
img_emb = model.embedder(img) ## blc
|
||||
img_emb = model.image_proj_model(img_emb)
|
||||
|
||||
cond_emb = model.get_learned_conditioning(prompts)
|
||||
cond = {"c_crossattn": [torch.cat([cond_emb,img_emb], dim=1)]}
|
||||
if model.model.conditioning_key == 'hybrid':
|
||||
z = get_latent_z(model, videos) # b c t h w
|
||||
if loop or interp:
|
||||
img_cat_cond = torch.zeros_like(z)
|
||||
img_cat_cond[:,:,0,:,:] = z[:,:,0,:,:]
|
||||
img_cat_cond[:,:,-1,:,:] = z[:,:,-1,:,:]
|
||||
else:
|
||||
img_cat_cond = z[:,:,:1,:,:]
|
||||
img_cat_cond = repeat(img_cat_cond, 'b c t h w -> b c (repeat t) h w', repeat=z.shape[2])
|
||||
cond["c_concat"] = [img_cat_cond] # b c 1 h w
|
||||
|
||||
if unconditional_guidance_scale != 1.0:
|
||||
if model.uncond_type == "empty_seq":
|
||||
prompts = batch_size * [""]
|
||||
uc_emb = model.get_learned_conditioning(prompts)
|
||||
elif model.uncond_type == "zero_embed":
|
||||
uc_emb = torch.zeros_like(cond_emb)
|
||||
uc_img_emb = model.embedder(torch.zeros_like(img)) ## b l c
|
||||
uc_img_emb = model.image_proj_model(uc_img_emb)
|
||||
uc = {"c_crossattn": [torch.cat([uc_emb,uc_img_emb],dim=1)]}
|
||||
if model.model.conditioning_key == 'hybrid':
|
||||
uc["c_concat"] = [img_cat_cond]
|
||||
else:
|
||||
uc = None
|
||||
|
||||
## we need one more unconditioning image=yes, text=""
|
||||
if multiple_cond_cfg and cfg_img != 1.0:
|
||||
uc_2 = {"c_crossattn": [torch.cat([uc_emb,img_emb],dim=1)]}
|
||||
if model.model.conditioning_key == 'hybrid':
|
||||
uc_2["c_concat"] = [img_cat_cond]
|
||||
kwargs.update({"unconditional_conditioning_img_nonetext": uc_2})
|
||||
else:
|
||||
kwargs.update({"unconditional_conditioning_img_nonetext": None})
|
||||
|
||||
z0 = None
|
||||
cond_mask = None
|
||||
|
||||
batch_variants = []
|
||||
for _ in range(n_samples):
|
||||
|
||||
if z0 is not None:
|
||||
cond_z0 = z0.clone()
|
||||
kwargs.update({"clean_cond": True})
|
||||
else:
|
||||
cond_z0 = None
|
||||
if ddim_sampler is not None:
|
||||
|
||||
samples, _ = ddim_sampler.sample(S=ddim_steps,
|
||||
conditioning=cond,
|
||||
batch_size=batch_size,
|
||||
shape=noise_shape[1:],
|
||||
verbose=False,
|
||||
unconditional_guidance_scale=unconditional_guidance_scale,
|
||||
unconditional_conditioning=uc,
|
||||
eta=ddim_eta,
|
||||
cfg_img=cfg_img,
|
||||
mask=cond_mask,
|
||||
x0=cond_z0,
|
||||
fs=fs,
|
||||
timestep_spacing=timestep_spacing,
|
||||
guidance_rescale=guidance_rescale,
|
||||
**kwargs
|
||||
)
|
||||
|
||||
## reconstruct from latent to pixel space
|
||||
batch_images = model.decode_first_stage(samples)
|
||||
batch_variants.append(batch_images)
|
||||
## variants, batch, c, t, h, w
|
||||
batch_variants = torch.stack(batch_variants)
|
||||
return batch_variants.permute(1, 0, 2, 3, 4, 5)
|
||||
|
||||
|
||||
def run_inference(args, gpu_num, gpu_no):
|
||||
## model config
|
||||
config = OmegaConf.load(args.config)
|
||||
model_config = config.pop("model", OmegaConf.create())
|
||||
|
||||
## set use_checkpoint as False as when using deepspeed, it encounters an error "deepspeed backend not set"
|
||||
model_config['params']['unet_config']['params']['use_checkpoint'] = False
|
||||
model = instantiate_from_config(model_config)
|
||||
model = model.cuda(gpu_no)
|
||||
model.perframe_ae = args.perframe_ae
|
||||
assert os.path.exists(args.ckpt_path), "Error: checkpoint Not Found!"
|
||||
model = load_model_checkpoint(model, args.ckpt_path)
|
||||
model.eval()
|
||||
|
||||
## run over data
|
||||
assert (args.height % 16 == 0) and (args.width % 16 == 0), "Error: image size [h,w] should be multiples of 16!"
|
||||
assert args.bs == 1, "Current implementation only support [batch size = 1]!"
|
||||
## latent noise shape
|
||||
h, w = args.height // 8, args.width // 8
|
||||
channels = model.model.diffusion_model.out_channels
|
||||
n_frames = args.video_length
|
||||
print(f'Inference with {n_frames} frames')
|
||||
noise_shape = [args.bs, channels, n_frames, h, w]
|
||||
|
||||
fakedir = os.path.join(args.savedir, "samples")
|
||||
fakedir_separate = os.path.join(args.savedir, "samples_separate")
|
||||
|
||||
# os.makedirs(fakedir, exist_ok=True)
|
||||
os.makedirs(fakedir_separate, exist_ok=True)
|
||||
|
||||
## prompt file setting
|
||||
assert os.path.exists(args.prompt_dir), "Error: prompt file Not Found!"
|
||||
filename_list, data_list, prompt_list = load_data_prompts(args.prompt_dir, video_size=(args.height, args.width), video_frames=n_frames, interp=args.interp)
|
||||
num_samples = len(prompt_list)
|
||||
samples_split = num_samples // gpu_num
|
||||
print('Prompts testing [rank:%d] %d/%d samples loaded.'%(gpu_no, samples_split, num_samples))
|
||||
#indices = random.choices(list(range(0, num_samples)), k=samples_per_device)
|
||||
indices = list(range(samples_split*gpu_no, samples_split*(gpu_no+1)))
|
||||
prompt_list_rank = [prompt_list[i] for i in indices]
|
||||
data_list_rank = [data_list[i] for i in indices]
|
||||
filename_list_rank = [filename_list[i] for i in indices]
|
||||
|
||||
start = time.time()
|
||||
with torch.no_grad(), torch.cuda.amp.autocast():
|
||||
for idx, indice in tqdm(enumerate(range(0, len(prompt_list_rank), args.bs)), desc='Sample Batch'):
|
||||
prompts = prompt_list_rank[indice:indice+args.bs]
|
||||
videos = data_list_rank[indice:indice+args.bs]
|
||||
filenames = filename_list_rank[indice:indice+args.bs]
|
||||
if isinstance(videos, list):
|
||||
videos = torch.stack(videos, dim=0).to("cuda")
|
||||
else:
|
||||
videos = videos.unsqueeze(0).to("cuda")
|
||||
|
||||
batch_samples = image_guided_synthesis(model, prompts, videos, noise_shape, args.n_samples, args.ddim_steps, args.ddim_eta, \
|
||||
args.unconditional_guidance_scale, args.cfg_img, args.frame_stride, args.text_input, args.multiple_cond_cfg, args.loop, args.interp, args.timestep_spacing, args.guidance_rescale)
|
||||
|
||||
## save each example individually
|
||||
for nn, samples in enumerate(batch_samples):
|
||||
## samples : [n_samples,c,t,h,w]
|
||||
prompt = prompts[nn]
|
||||
filename = filenames[nn]
|
||||
# save_results(prompt, samples, filename, fakedir, fps=8, loop=args.loop)
|
||||
save_results_seperate(prompt, samples, filename, fakedir, fps=8, loop=args.loop)
|
||||
|
||||
print(f"Saved in {args.savedir}. Time used: {(time.time() - start):.2f} seconds")
|
||||
|
||||
|
||||
def get_parser():
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--savedir", type=str, default=None, help="results saving path")
|
||||
parser.add_argument("--ckpt_path", type=str, default=None, help="checkpoint path")
|
||||
parser.add_argument("--config", type=str, help="config (yaml) path")
|
||||
parser.add_argument("--prompt_dir", type=str, default=None, help="a data dir containing videos and prompts")
|
||||
parser.add_argument("--n_samples", type=int, default=1, help="num of samples per prompt",)
|
||||
parser.add_argument("--ddim_steps", type=int, default=50, help="steps of ddim if positive, otherwise use DDPM",)
|
||||
parser.add_argument("--ddim_eta", type=float, default=1.0, help="eta for ddim sampling (0.0 yields deterministic sampling)",)
|
||||
parser.add_argument("--bs", type=int, default=1, help="batch size for inference, should be one")
|
||||
parser.add_argument("--height", type=int, default=512, help="image height, in pixel space")
|
||||
parser.add_argument("--width", type=int, default=512, help="image width, in pixel space")
|
||||
parser.add_argument("--frame_stride", type=int, default=3, help="frame stride control for 256 model (larger->larger motion), FPS control for 512 or 1024 model (smaller->larger motion)")
|
||||
parser.add_argument("--unconditional_guidance_scale", type=float, default=1.0, help="prompt classifier-free guidance")
|
||||
parser.add_argument("--seed", type=int, default=123, help="seed for seed_everything")
|
||||
parser.add_argument("--video_length", type=int, default=16, help="inference video length")
|
||||
parser.add_argument("--negative_prompt", action='store_true', default=False, help="negative prompt")
|
||||
parser.add_argument("--text_input", action='store_true', default=False, help="input text to I2V model or not")
|
||||
parser.add_argument("--multiple_cond_cfg", action='store_true', default=False, help="use multi-condition cfg or not")
|
||||
parser.add_argument("--cfg_img", type=float, default=None, help="guidance scale for image conditioning")
|
||||
parser.add_argument("--timestep_spacing", type=str, default="uniform", help="The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information.")
|
||||
parser.add_argument("--guidance_rescale", type=float, default=0.0, help="guidance rescale in [Common Diffusion Noise Schedules and Sample Steps are Flawed](https://huggingface.co/papers/2305.08891)")
|
||||
parser.add_argument("--perframe_ae", action='store_true', default=False, help="if we use per-frame AE decoding, set it to True to save GPU memory, especially for the model of 576x1024")
|
||||
|
||||
## currently not support looping video and generative frame interpolation
|
||||
parser.add_argument("--loop", action='store_true', default=False, help="generate looping videos or not")
|
||||
parser.add_argument("--interp", action='store_true', default=False, help="generate generative frame interpolation or not")
|
||||
return parser
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
now = datetime.datetime.now().strftime("%Y-%m-%d-%H-%M-%S")
|
||||
print("@DynamiCrafter cond-Inference: %s"%now)
|
||||
parser = get_parser()
|
||||
args = parser.parse_args()
|
||||
|
||||
seed_everything(args.seed)
|
||||
rank, gpu_num = 0, 1
|
||||
run_inference(args, gpu_num, rank)
|
||||
@@ -0,0 +1,107 @@
|
||||
import os
|
||||
import time
|
||||
from omegaconf import OmegaConf
|
||||
import torch
|
||||
from scripts.evaluation.funcs import load_model_checkpoint, save_videos, batch_ddim_sampling, get_latent_z
|
||||
from utils.utils import instantiate_from_config
|
||||
from huggingface_hub import hf_hub_download
|
||||
from einops import repeat
|
||||
import torchvision.transforms as transforms
|
||||
from pytorch_lightning import seed_everything
|
||||
|
||||
|
||||
class Image2Video():
|
||||
def __init__(self,result_dir='./tmp/',gpu_num=1,resolution='256_256') -> None:
|
||||
self.resolution = (int(resolution.split('_')[0]), int(resolution.split('_')[1])) #hw
|
||||
self.download_model()
|
||||
|
||||
self.result_dir = result_dir
|
||||
if not os.path.exists(self.result_dir):
|
||||
os.mkdir(self.result_dir)
|
||||
ckpt_path='checkpoints/dynamicrafter_'+resolution.split('_')[1]+'_v1/model.ckpt'
|
||||
config_file='configs/inference_'+resolution.split('_')[1]+'_v1.0.yaml'
|
||||
config = OmegaConf.load(config_file)
|
||||
model_config = config.pop("model", OmegaConf.create())
|
||||
model_config['params']['unet_config']['params']['use_checkpoint']=False
|
||||
model_list = []
|
||||
for gpu_id in range(gpu_num):
|
||||
model = instantiate_from_config(model_config)
|
||||
# model = model.cuda(gpu_id)
|
||||
assert os.path.exists(ckpt_path), "Error: checkpoint Not Found!"
|
||||
model = load_model_checkpoint(model, ckpt_path)
|
||||
model.eval().half()
|
||||
model_list.append(model)
|
||||
self.model_list = model_list
|
||||
self.save_fps = 8
|
||||
|
||||
def get_image(self, image, prompt, steps=50, cfg_scale=7.5, eta=1.0, fs=3, seed=123):
|
||||
seed_everything(seed)
|
||||
transform = transforms.Compose([
|
||||
transforms.Resize(min(self.resolution)),
|
||||
transforms.CenterCrop(self.resolution),
|
||||
])
|
||||
torch.cuda.empty_cache()
|
||||
print('start:', prompt, time.strftime('%Y-%m-%d %H:%M:%S',time.localtime(time.time())))
|
||||
start = time.time()
|
||||
gpu_id=0
|
||||
if steps > 60:
|
||||
steps = 60
|
||||
model = self.model_list[gpu_id]
|
||||
model = model.cuda()
|
||||
batch_size=1
|
||||
channels = model.model.diffusion_model.out_channels
|
||||
frames = model.temporal_length
|
||||
h, w = self.resolution[0] // 8, self.resolution[1] // 8
|
||||
noise_shape = [batch_size, channels, frames, h, w]
|
||||
|
||||
# text cond
|
||||
with torch.no_grad(), torch.cuda.amp.autocast():
|
||||
text_emb = model.get_learned_conditioning([prompt])
|
||||
|
||||
# img cond
|
||||
img_tensor = torch.from_numpy(image).permute(2, 0, 1).float().to(model.device)
|
||||
img_tensor = (img_tensor / 255. - 0.5) * 2
|
||||
|
||||
image_tensor_resized = transform(img_tensor) #3,h,w
|
||||
videos = image_tensor_resized.unsqueeze(0) # bchw
|
||||
|
||||
z = get_latent_z(model, videos.unsqueeze(2)) #bc,1,hw
|
||||
|
||||
img_tensor_repeat = repeat(z, 'b c t h w -> b c (repeat t) h w', repeat=frames)
|
||||
|
||||
cond_images = model.embedder(img_tensor.unsqueeze(0)) ## blc
|
||||
img_emb = model.image_proj_model(cond_images)
|
||||
|
||||
imtext_cond = torch.cat([text_emb, img_emb], dim=1)
|
||||
|
||||
fs = torch.tensor([fs], dtype=torch.long, device=model.device)
|
||||
cond = {"c_crossattn": [imtext_cond], "fs": fs, "c_concat": [img_tensor_repeat]}
|
||||
|
||||
## inference
|
||||
batch_samples = batch_ddim_sampling(model, cond, noise_shape, n_samples=1, ddim_steps=steps, ddim_eta=eta, cfg_scale=cfg_scale)
|
||||
## b,samples,c,t,h,w
|
||||
prompt_str = prompt.replace("/", "_slash_") if "/" in prompt else prompt
|
||||
prompt_str = prompt_str.replace(" ", "_") if " " in prompt else prompt_str
|
||||
prompt_str=prompt_str[:40]
|
||||
if len(prompt_str) == 0:
|
||||
prompt_str = 'empty_prompt'
|
||||
|
||||
save_videos(batch_samples, self.result_dir, filenames=[prompt_str], fps=self.save_fps)
|
||||
print(f"Saved in {prompt_str}. Time used: {(time.time() - start):.2f} seconds")
|
||||
model = model.cpu()
|
||||
return os.path.join(self.result_dir, f"{prompt_str}.mp4")
|
||||
|
||||
def download_model(self):
|
||||
REPO_ID = 'Doubiiu/DynamiCrafter_'+str(self.resolution[1]) if self.resolution[1]!=256 else 'Doubiiu/DynamiCrafter'
|
||||
filename_list = ['model.ckpt']
|
||||
if not os.path.exists('./checkpoints/dynamicrafter_'+str(self.resolution[1])+'_v1/'):
|
||||
os.makedirs('./checkpoints/dynamicrafter_'+str(self.resolution[1])+'_v1/')
|
||||
for filename in filename_list:
|
||||
local_file = os.path.join('./checkpoints/dynamicrafter_'+str(self.resolution[1])+'_v1/', filename)
|
||||
if not os.path.exists(local_file):
|
||||
hf_hub_download(repo_id=REPO_ID, filename=filename, local_dir='./checkpoints/dynamicrafter_'+str(self.resolution[1])+'_v1/', local_dir_use_symlinks=False)
|
||||
|
||||
if __name__ == '__main__':
|
||||
i2v = Image2Video()
|
||||
video_path = i2v.get_image('prompts/art.png','man fishing in a boat at sunset')
|
||||
print('done', video_path)
|
||||
@@ -0,0 +1,131 @@
|
||||
import os
|
||||
import time
|
||||
from omegaconf import OmegaConf
|
||||
import torch
|
||||
from scripts.evaluation.funcs import load_model_checkpoint, save_videos, batch_ddim_sampling, get_latent_z
|
||||
from utils.utils import instantiate_from_config
|
||||
from huggingface_hub import hf_hub_download
|
||||
from einops import repeat
|
||||
import torchvision.transforms as transforms
|
||||
from pytorch_lightning import seed_everything
|
||||
|
||||
|
||||
class Image2Video():
|
||||
def __init__(self,result_dir='./tmp/',gpu_num=1,resolution='256_256') -> None:
|
||||
self.resolution = (int(resolution.split('_')[0]), int(resolution.split('_')[1])) #hw
|
||||
self.download_model()
|
||||
|
||||
self.result_dir = result_dir
|
||||
if not os.path.exists(self.result_dir):
|
||||
os.mkdir(self.result_dir)
|
||||
ckpt_path='checkpoints/dynamicrafter_'+resolution.split('_')[1]+'_interp_v1/model.ckpt'
|
||||
config_file='configs/inference_'+resolution.split('_')[1]+'_v1.0.yaml'
|
||||
config = OmegaConf.load(config_file)
|
||||
model_config = config.pop("model", OmegaConf.create())
|
||||
model_config['params']['unet_config']['params']['use_checkpoint']=False
|
||||
model_list = []
|
||||
for gpu_id in range(gpu_num):
|
||||
model = instantiate_from_config(model_config)
|
||||
# model = model.cuda(gpu_id)
|
||||
assert os.path.exists(ckpt_path), "Error: checkpoint Not Found!"
|
||||
model = load_model_checkpoint(model, ckpt_path)
|
||||
model.eval()
|
||||
model_list.append(model)
|
||||
self.model_list = model_list
|
||||
self.save_fps = 8
|
||||
|
||||
def get_image(self, image, prompt, steps=50, cfg_scale=7.5, eta=1.0, fs=3, seed=123, image2=None):
|
||||
seed_everything(seed)
|
||||
transform = transforms.Compose([
|
||||
transforms.Resize(min(self.resolution)),
|
||||
transforms.CenterCrop(self.resolution),
|
||||
])
|
||||
torch.cuda.empty_cache()
|
||||
print('start:', prompt, time.strftime('%Y-%m-%d %H:%M:%S',time.localtime(time.time())))
|
||||
start = time.time()
|
||||
gpu_id=0
|
||||
if steps > 60:
|
||||
steps = 60
|
||||
model = self.model_list[gpu_id]
|
||||
model = model.cuda()
|
||||
batch_size=1
|
||||
channels = model.model.diffusion_model.out_channels
|
||||
frames = model.temporal_length
|
||||
h, w = self.resolution[0] // 8, self.resolution[1] // 8
|
||||
noise_shape = [batch_size, channels, frames, h, w]
|
||||
|
||||
# text cond
|
||||
with torch.no_grad(), torch.cuda.amp.autocast():
|
||||
text_emb = model.get_learned_conditioning([prompt])
|
||||
|
||||
# img cond
|
||||
img_tensor = torch.from_numpy(image).permute(2, 0, 1).float().to(model.device)
|
||||
img_tensor = (img_tensor / 255. - 0.5) * 2
|
||||
|
||||
image_tensor_resized = transform(img_tensor) #3,h,w
|
||||
videos = image_tensor_resized.unsqueeze(0) # bchw
|
||||
|
||||
z = get_latent_z(model, videos.unsqueeze(2)) #bc,1,hw
|
||||
|
||||
|
||||
if image2 is not None:
|
||||
img_tensor2 = torch.from_numpy(image2).permute(2, 0, 1).float().to(model.device)
|
||||
img_tensor2 = (img_tensor2 / 255. - 0.5) * 2
|
||||
|
||||
image_tensor_resized2 = transform(img_tensor2) #3,h,w
|
||||
videos2 = image_tensor_resized2.unsqueeze(0) # bchw
|
||||
|
||||
z2 = get_latent_z(model, videos2.unsqueeze(2)) #bc,1,hw
|
||||
|
||||
img_tensor_repeat = repeat(z, 'b c t h w -> b c (repeat t) h w', repeat=frames)
|
||||
|
||||
img_tensor_repeat = torch.zeros_like(img_tensor_repeat)
|
||||
|
||||
## old
|
||||
img_tensor_repeat[:,:,:1,:,:] = z
|
||||
if image2 is not None:
|
||||
img_tensor_repeat[:,:,-1:,:,:] = z2
|
||||
else:
|
||||
img_tensor_repeat[:,:,-1:,:,:] = z
|
||||
|
||||
|
||||
cond_images = model.embedder(img_tensor.unsqueeze(0)) ## blc
|
||||
img_emb = model.image_proj_model(cond_images)
|
||||
|
||||
imtext_cond = torch.cat([text_emb, img_emb], dim=1)
|
||||
|
||||
fs = torch.tensor([fs], dtype=torch.long, device=model.device)
|
||||
cond = {"c_crossattn": [imtext_cond], "fs": fs, "c_concat": [img_tensor_repeat]}
|
||||
|
||||
## inference
|
||||
batch_samples = batch_ddim_sampling(model, cond, noise_shape, n_samples=1, ddim_steps=steps, ddim_eta=eta, cfg_scale=cfg_scale)
|
||||
|
||||
## remove the last frame
|
||||
if image2 is None:
|
||||
batch_samples = batch_samples[:,:,:,:-1,...]
|
||||
## b,samples,c,t,h,w
|
||||
prompt_str = prompt.replace("/", "_slash_") if "/" in prompt else prompt
|
||||
prompt_str = prompt_str.replace(" ", "_") if " " in prompt else prompt_str
|
||||
prompt_str=prompt_str[:40]
|
||||
if len(prompt_str) == 0:
|
||||
prompt_str = 'empty_prompt'
|
||||
|
||||
save_videos(batch_samples, self.result_dir, filenames=[prompt_str], fps=self.save_fps)
|
||||
print(f"Saved in {prompt_str}. Time used: {(time.time() - start):.2f} seconds")
|
||||
model = model.cpu()
|
||||
return os.path.join(self.result_dir, f"{prompt_str}.mp4")
|
||||
|
||||
def download_model(self):
|
||||
REPO_ID = 'Doubiiu/DynamiCrafter_'+str(self.resolution[1])+'_Interp'
|
||||
filename_list = ['model.ckpt']
|
||||
if not os.path.exists('./checkpoints/dynamicrafter_'+str(self.resolution[1])+'_interp_v1/'):
|
||||
os.makedirs('./checkpoints/dynamicrafter_'+str(self.resolution[1])+'_interp_v1/')
|
||||
for filename in filename_list:
|
||||
local_file = os.path.join('./checkpoints/dynamicrafter_'+str(self.resolution[1])+'_interp_v1/', filename)
|
||||
if not os.path.exists(local_file):
|
||||
hf_hub_download(repo_id=REPO_ID, filename=filename, local_dir='./checkpoints/dynamicrafter_'+str(self.resolution[1])+'_interp_v1/', local_dir_use_symlinks=False)
|
||||
|
||||
if __name__ == '__main__':
|
||||
i2v = Image2Video()
|
||||
video_path = i2v.get_image('prompts/art.png','man fishing in a boat at sunset')
|
||||
print('done', video_path)
|
||||
@@ -0,0 +1,61 @@
|
||||
version=$1 ##1024, 512, 256
|
||||
seed=123
|
||||
name=dynamicrafter_$1_seed${seed}
|
||||
|
||||
ckpt=checkpoints/dynamicrafter_$1_v1/model.ckpt
|
||||
config=configs/inference_$1_v1.0.yaml
|
||||
|
||||
prompt_dir=prompts/$1/
|
||||
res_dir="results"
|
||||
|
||||
if [ "$1" == "256" ]; then
|
||||
H=256
|
||||
FS=3 ## This model adopts frame stride=3, range recommended: 1-6 (larger value -> larger motion)
|
||||
elif [ "$1" == "512" ]; then
|
||||
H=320
|
||||
FS=24 ## This model adopts FPS=24, range recommended: 15-30 (smaller value -> larger motion)
|
||||
elif [ "$1" == "1024" ]; then
|
||||
H=576
|
||||
FS=10 ## This model adopts FPS=10, range recommended: 15-5 (smaller value -> larger motion)
|
||||
else
|
||||
echo "Invalid input. Please enter 256, 512, or 1024."
|
||||
exit 1
|
||||
fi
|
||||
|
||||
if [ "$1" == "256" ]; then
|
||||
CUDA_VISIBLE_DEVICES=0 python3 scripts/evaluation/inference.py \
|
||||
--seed ${seed} \
|
||||
--ckpt_path $ckpt \
|
||||
--config $config \
|
||||
--savedir $res_dir/$name \
|
||||
--n_samples 1 \
|
||||
--bs 1 --height ${H} --width $1 \
|
||||
--unconditional_guidance_scale 7.5 \
|
||||
--ddim_steps 50 \
|
||||
--ddim_eta 1.0 \
|
||||
--prompt_dir $prompt_dir \
|
||||
--text_input \
|
||||
--video_length 16 \
|
||||
--frame_stride ${FS}
|
||||
else
|
||||
CUDA_VISIBLE_DEVICES=0 python3 scripts/evaluation/inference.py \
|
||||
--seed ${seed} \
|
||||
--ckpt_path $ckpt \
|
||||
--config $config \
|
||||
--savedir $res_dir/$name \
|
||||
--n_samples 1 \
|
||||
--bs 1 --height ${H} --width $1 \
|
||||
--unconditional_guidance_scale 7.5 \
|
||||
--ddim_steps 50 \
|
||||
--ddim_eta 1.0 \
|
||||
--prompt_dir $prompt_dir \
|
||||
--text_input \
|
||||
--video_length 16 \
|
||||
--frame_stride ${FS} \
|
||||
--timestep_spacing 'uniform_trailing' --guidance_rescale 0.7 --perframe_ae
|
||||
fi
|
||||
|
||||
|
||||
## multi-cond CFG: the <unconditional_guidance_scale> is s_txt, <cfg_img> is s_img
|
||||
#--multiple_cond_cfg --cfg_img 7.5
|
||||
#--loop
|
||||
@@ -0,0 +1,47 @@
|
||||
version=$1 # interp or loop
|
||||
ckpt=checkpoints/dynamicrafter_512_interp_v1/model.ckpt
|
||||
config=configs/inference_512_v1.0.yaml
|
||||
|
||||
prompt_dir=prompts/512_$1/
|
||||
res_dir="results"
|
||||
|
||||
FS=5 ## This model adopts FPS=5, range recommended: 5-30 (smaller value -> larger motion)
|
||||
|
||||
|
||||
if [ "$1" == "interp" ]; then
|
||||
seed=12306
|
||||
name=dynamicrafter_512_$1_seed${seed}
|
||||
CUDA_VISIBLE_DEVICES=0 python3 scripts/evaluation/inference.py \
|
||||
--seed ${seed} \
|
||||
--ckpt_path $ckpt \
|
||||
--config $config \
|
||||
--savedir $res_dir/$name \
|
||||
--n_samples 1 \
|
||||
--bs 1 --height 320 --width 512 \
|
||||
--unconditional_guidance_scale 7.5 \
|
||||
--ddim_steps 50 \
|
||||
--ddim_eta 1.0 \
|
||||
--prompt_dir $prompt_dir \
|
||||
--text_input \
|
||||
--video_length 16 \
|
||||
--frame_stride ${FS} \
|
||||
--timestep_spacing 'uniform_trailing' --guidance_rescale 0.7 --perframe_ae --interp
|
||||
else
|
||||
seed=234
|
||||
name=dynamicrafter_512_$1_seed${seed}
|
||||
CUDA_VISIBLE_DEVICES=0 python3 scripts/evaluation/inference.py \
|
||||
--seed ${seed} \
|
||||
--ckpt_path $ckpt \
|
||||
--config $config \
|
||||
--savedir $res_dir/$name \
|
||||
--n_samples 1 \
|
||||
--bs 1 --height 320 --width 512 \
|
||||
--unconditional_guidance_scale 7.5 \
|
||||
--ddim_steps 50 \
|
||||
--ddim_eta 1.0 \
|
||||
--prompt_dir $prompt_dir \
|
||||
--text_input \
|
||||
--video_length 16 \
|
||||
--frame_stride ${FS} \
|
||||
--timestep_spacing 'uniform_trailing' --guidance_rescale 0.7 --perframe_ae --loop
|
||||
fi
|
||||
@@ -0,0 +1,102 @@
|
||||
version=$1 ##1024, 512, 256
|
||||
seed=123
|
||||
|
||||
name=dynamicrafter_$1_mp_seed${seed}
|
||||
|
||||
ckpt=checkpoints/dynamicrafter_$1_v1/model.ckpt
|
||||
config=configs/inference_$1_v1.0.yaml
|
||||
|
||||
prompt_dir=prompts/$1/
|
||||
res_dir="results"
|
||||
|
||||
if [ "$1" == "256" ]; then
|
||||
H=256
|
||||
FS=3 ## This model adopts frame stride=3
|
||||
elif [ "$1" == "512" ]; then
|
||||
H=320
|
||||
FS=24 ## This model adopts FPS=24
|
||||
elif [ "$1" == "1024" ]; then
|
||||
H=576
|
||||
FS=10 ## This model adopts FPS=10
|
||||
else
|
||||
echo "Invalid input. Please enter 256, 512, or 1024."
|
||||
exit 1
|
||||
fi
|
||||
|
||||
# if [ "$1" == "256" ]; then
|
||||
# CUDA_VISIBLE_DEVICES=2 python3 scripts/evaluation/inference.py \
|
||||
# --seed 123 \
|
||||
# --ckpt_path $ckpt \
|
||||
# --config $config \
|
||||
# --savedir $res_dir/$name \
|
||||
# --n_samples 1 \
|
||||
# --bs 1 --height ${H} --width $1 \
|
||||
# --unconditional_guidance_scale 7.5 \
|
||||
# --ddim_steps 50 \
|
||||
# --ddim_eta 1.0 \
|
||||
# --prompt_dir $prompt_dir \
|
||||
# --text_input \
|
||||
# --video_length 16 \
|
||||
# --frame_stride ${FS}
|
||||
# else
|
||||
# CUDA_VISIBLE_DEVICES=2 python3 scripts/evaluation/inference.py \
|
||||
# --seed 123 \
|
||||
# --ckpt_path $ckpt \
|
||||
# --config $config \
|
||||
# --savedir $res_dir/$name \
|
||||
# --n_samples 1 \
|
||||
# --bs 1 --height ${H} --width $1 \
|
||||
# --unconditional_guidance_scale 7.5 \
|
||||
# --ddim_steps 50 \
|
||||
# --ddim_eta 1.0 \
|
||||
# --prompt_dir $prompt_dir \
|
||||
# --text_input \
|
||||
# --video_length 16 \
|
||||
# --frame_stride ${FS} \
|
||||
# --timestep_spacing 'uniform_trailing' --guidance_rescale 0.7
|
||||
# fi
|
||||
|
||||
|
||||
## multi-cond CFG: the <unconditional_guidance_scale> is s_txt, <cfg_img> is s_img
|
||||
#--multiple_cond_cfg --cfg_img 7.5
|
||||
#--loop
|
||||
|
||||
## inference using single node with multi-GPUs:
|
||||
if [ "$1" == "256" ]; then
|
||||
CUDA_VISIBLE_DEVICES=0,1,2,3,4,5,6,7 python3 -m torch.distributed.launch \
|
||||
--nproc_per_node=8 --nnodes=1 --master_addr=127.0.0.1 --master_port=23456 --node_rank=0 \
|
||||
scripts/evaluation/ddp_wrapper.py \
|
||||
--module 'inference' \
|
||||
--seed ${seed} \
|
||||
--ckpt_path $ckpt \
|
||||
--config $config \
|
||||
--savedir $res_dir/$name \
|
||||
--n_samples 1 \
|
||||
--bs 1 --height ${H} --width $1 \
|
||||
--unconditional_guidance_scale 7.5 \
|
||||
--ddim_steps 50 \
|
||||
--ddim_eta 1.0 \
|
||||
--prompt_dir $prompt_dir \
|
||||
--text_input \
|
||||
--video_length 16 \
|
||||
--frame_stride ${FS}
|
||||
else
|
||||
CUDA_VISIBLE_DEVICES=0,1,2,3,4,5,6,7 python3 -m torch.distributed.launch \
|
||||
--nproc_per_node=8 --nnodes=1 --master_addr=127.0.0.1 --master_port=23456 --node_rank=0 \
|
||||
scripts/evaluation/ddp_wrapper.py \
|
||||
--module 'inference' \
|
||||
--seed ${seed} \
|
||||
--ckpt_path $ckpt \
|
||||
--config $config \
|
||||
--savedir $res_dir/$name \
|
||||
--n_samples 1 \
|
||||
--bs 1 --height ${H} --width $1 \
|
||||
--unconditional_guidance_scale 7.5 \
|
||||
--ddim_steps 50 \
|
||||
--ddim_eta 1.0 \
|
||||
--prompt_dir $prompt_dir \
|
||||
--text_input \
|
||||
--video_length 16 \
|
||||
--frame_stride ${FS} \
|
||||
--timestep_spacing 'uniform_trailing' --guidance_rescale 0.7 --perframe_ae
|
||||
fi
|
||||
@@ -0,0 +1,79 @@
|
||||
import importlib
|
||||
import numpy as np
|
||||
import cv2
|
||||
import torch
|
||||
import torch.distributed as dist
|
||||
import os
|
||||
|
||||
|
||||
def count_params(model, verbose=False):
|
||||
total_params = sum(p.numel() for p in model.parameters())
|
||||
if verbose:
|
||||
print(f"{model.__class__.__name__} has {total_params*1.e-6:.2f} M params.")
|
||||
return total_params
|
||||
|
||||
|
||||
def check_istarget(name, para_list):
|
||||
"""
|
||||
name: full name of source para
|
||||
para_list: partial name of target para
|
||||
"""
|
||||
istarget=False
|
||||
for para in para_list:
|
||||
if para in name:
|
||||
return True
|
||||
return istarget
|
||||
|
||||
|
||||
def instantiate_from_config(config):
|
||||
if not "target" in config:
|
||||
if config == '__is_first_stage__':
|
||||
return None
|
||||
elif config == "__is_unconditional__":
|
||||
return None
|
||||
raise KeyError("Expected key `target` to instantiate.")
|
||||
return get_obj_from_str(config["target"])(**config.get("params", dict()))
|
||||
|
||||
|
||||
def get_obj_from_str(string, reload=False):
|
||||
package_directory_name = os.path.basename(os.path.dirname(os.path.dirname(os.path.abspath(__file__))))
|
||||
module, cls = string.rsplit(".", 1)
|
||||
if reload:
|
||||
module_imp = importlib.import_module(module)
|
||||
importlib.reload(module_imp)
|
||||
return getattr(importlib.import_module(module, package=package_directory_name), cls)
|
||||
|
||||
|
||||
def load_npz_from_dir(data_dir):
|
||||
data = [np.load(os.path.join(data_dir, data_name))['arr_0'] for data_name in os.listdir(data_dir)]
|
||||
data = np.concatenate(data, axis=0)
|
||||
return data
|
||||
|
||||
|
||||
def load_npz_from_paths(data_paths):
|
||||
data = [np.load(data_path)['arr_0'] for data_path in data_paths]
|
||||
data = np.concatenate(data, axis=0)
|
||||
return data
|
||||
|
||||
|
||||
def resize_numpy_image(image, max_resolution=512 * 512, resize_short_edge=None):
|
||||
h, w = image.shape[:2]
|
||||
if resize_short_edge is not None:
|
||||
k = resize_short_edge / min(h, w)
|
||||
else:
|
||||
k = max_resolution / (h * w)
|
||||
k = k**0.5
|
||||
h = int(np.round(h * k / 64)) * 64
|
||||
w = int(np.round(w * k / 64)) * 64
|
||||
image = cv2.resize(image, (w, h), interpolation=cv2.INTER_LANCZOS4)
|
||||
return image
|
||||
|
||||
|
||||
def setup_dist(args):
|
||||
if dist.is_initialized():
|
||||
return
|
||||
torch.cuda.set_device(args.local_rank)
|
||||
torch.distributed.init_process_group(
|
||||
'nccl',
|
||||
init_method='env://'
|
||||
)
|
||||