1.6.7
This commit is contained in:
 noembryo
+1
-2
@@ -2,8 +2,7 @@
|
||||
/XTRA
|
||||
/__pycache__
|
||||
/.idea
|
||||
/js
|
||||
/TermList*.json
|
||||
/___backup.pyw
|
||||
/load_image_from_dir.py
|
||||
/ComfyUI-noEmbryo.iml
|
||||
*.pyc
|
||||
|
||||
@@ -17,7 +17,6 @@ You can access them through "Add node > noEmbryo" submenu.
|
||||
---
|
||||
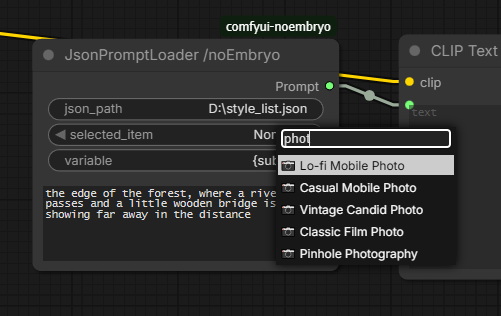
## Json Prompt Loader
|
||||
|
||||
|
||||
A node that can load a `.json` file with `item:prompt` pairs and outputs the selected item's prompt, while combining it with a custom prompt.
|
||||
It can load `.json` files from any directory, not just the node's directory.
|
||||
For the custom text integration, there is a variable (can be specified by the user), that can be used in the item's prompt text to insert the custom text anywhere in the body of the prompt.
|
||||
@@ -117,7 +116,6 @@ A node that "chops" a text using a regular expression and outputs the chopped pa
|
||||
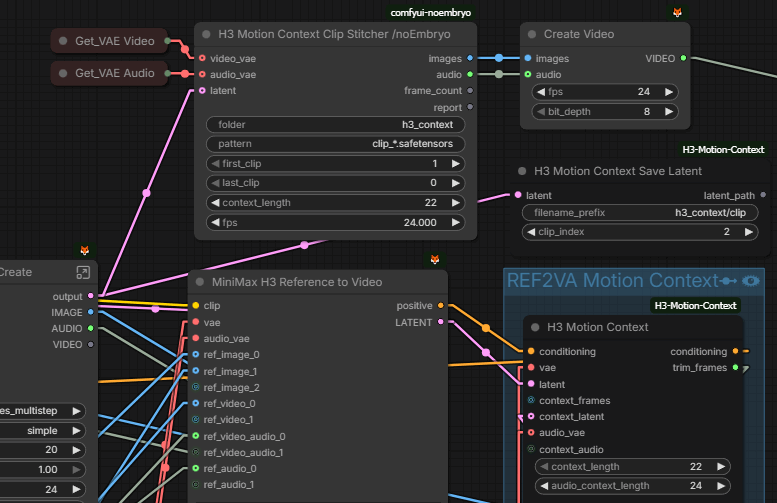
## H3 Motion Context Clip Stitcher
|
||||
|
||||
|
||||
|
||||
Final assembly for [NikoDemon80's H3 Motion Context](https://github.com/NikoDemon80/ComfyUI-H3-Motion-Context) AV clip archives.
|
||||
|
||||
It loads numbered h3_motion_context_av_v1 files (clip_xx.safetensors), decodes one clip at a time to avoid memory peaks, dissolves the overlap between adjacent clips (video + synchronized audio), and concatenates them to a final video and audio stream.
|
||||
@@ -148,7 +146,7 @@ No quality loss, like when trying to concatenate encoded videos.
|
||||
---
|
||||
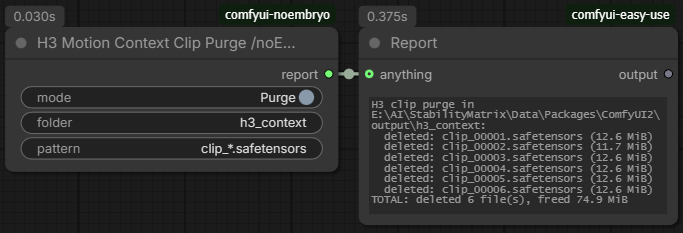
## H3 Motion Context Clip Purge
|
||||
|
||||
Deletes the numbered `h3_motion_context_av_v1` clip archive files at the root of a folder (default: `h3_context`)
|
||||
Deletes the numbered `h3_motion_context_av_v1` clip archive files at the root of a folder (default: `h3_context`).
|
||||
Only files matching the pattern are removed; sub-folders and everything inside them are left untouched.
|
||||
|
||||
- **Controls**
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
import hashlib
|
||||
import io
|
||||
import math
|
||||
import os
|
||||
import json
|
||||
import shutil
|
||||
@@ -12,7 +13,6 @@ from urllib.error import URLError
|
||||
from PIL import (Image, ImageOps, ImageSequence, ImageFile, UnidentifiedImageError, )
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
import folder_paths
|
||||
from aiohttp import web
|
||||
from server import PromptServer
|
||||
@@ -94,9 +94,13 @@ def _pillow(fn, arg):
|
||||
return x
|
||||
|
||||
|
||||
def _pil_to_image_mask(img: 'Image.Image | Iterable[Image.Image]',
|
||||
output_image: 'list[torch.Tensor] | None',
|
||||
output_mask: 'list[torch.Tensor] | None'):
|
||||
def _pil_to_image_mask(img, output_image, output_mask):
|
||||
"""
|
||||
|
||||
:type img: Image.Image | Iterable[Image.Image]
|
||||
:type output_image: list[torch.Tensor] | None
|
||||
:type output_mask: list[torch.Tensor] | None
|
||||
"""
|
||||
output_images = []
|
||||
output_masks = []
|
||||
w, h = None, None
|
||||
@@ -278,7 +282,7 @@ class LoadImageFromPathEnhanced:
|
||||
" and height are connected, when set (not 0), and"
|
||||
" it overrides max_megapixels.", }), }, }
|
||||
|
||||
CATEGORY = "noEmbryo"
|
||||
CATEGORY = "noEmbryo/Image"
|
||||
RETURN_TYPES = ("IMAGE", "MASK", "STRING")
|
||||
RETURN_NAMES = ("IMAGE", "MASK", "path")
|
||||
FUNCTION = "load_image_enhanced"
|
||||
@@ -449,6 +453,304 @@ class LoadImageFromPathEnhanced:
|
||||
return True
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# ImageComposer — compose several IMAGE inputs into one sheet.
|
||||
# Natural sizing only: one shared scale factor (never above 1), skyline
|
||||
# packing, tightest arrangement. The packing is mirrored in JS
|
||||
# (web/js/image_nodes.js) for the live on-node preview.
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
_EPS = 1e-9
|
||||
_ALIGN = 16
|
||||
_IC_BACKGROUNDS = {"black": 0.0, "grey": 0.5, "white": 1.0}
|
||||
_IC_PACK_ASPECT_MIN = 0.45
|
||||
_IC_PACK_ASPECT_MAX = 2.2
|
||||
_IC_PACK_WIDTH_STEPS = 48
|
||||
_IC_MAX_IMAGES = 16
|
||||
|
||||
|
||||
def _ic_skyline_pack(sizes, width, gap):
|
||||
""" Place rectangles bottom-left into a strip `width` wide.
|
||||
|
||||
Returns (placements, w0, h0) in source pixels, or None if anything
|
||||
does not fit. Placements are (x, y, w, h), in the order given.
|
||||
Nothing is ever rotated.
|
||||
"""
|
||||
sky = [(0.0, width, 0.0)]
|
||||
placed = []
|
||||
for w, h in sizes:
|
||||
iw = w + gap
|
||||
ih = h + gap
|
||||
if iw > width + _EPS:
|
||||
return None
|
||||
best = None
|
||||
for i in range(len(sky)):
|
||||
start = sky[i][0]
|
||||
if start + iw > width + _EPS:
|
||||
continue
|
||||
y = 0.0
|
||||
span = iw
|
||||
j = i
|
||||
while span > _EPS and j < len(sky):
|
||||
if sky[j][2] > y:
|
||||
y = sky[j][2]
|
||||
span -= sky[j][1]
|
||||
j += 1
|
||||
if span > _EPS:
|
||||
continue # ran off the right-hand end
|
||||
if best is None or (y, start) < best:
|
||||
best = (y, start)
|
||||
if best is None:
|
||||
return None
|
||||
y, x = best
|
||||
placed.append((x, y, w, h))
|
||||
# Cut the covered span out of the skyline and lay the new top
|
||||
# over it, then merge neighbours at the same height.
|
||||
cut = []
|
||||
end = x + iw
|
||||
for sx, sw, sy in sky:
|
||||
if sx + sw <= x + _EPS or sx >= end - _EPS:
|
||||
cut.append((sx, sw, sy))
|
||||
continue
|
||||
if sx < x:
|
||||
cut.append((sx, x - sx, sy))
|
||||
if sx + sw > end:
|
||||
cut.append((end, sx + sw - end, sy))
|
||||
cut.append((x, iw, y + ih))
|
||||
cut.sort(key=lambda seg_: seg_[0])
|
||||
merged = []
|
||||
for seg in cut:
|
||||
if merged and abs(merged[-1][2] - seg[2]) < _EPS:
|
||||
merged[-1] = (merged[-1][0], merged[-1][1] + seg[1], seg[2])
|
||||
else:
|
||||
merged.append(seg)
|
||||
sky = merged
|
||||
|
||||
w0 = max(p[0] + p[2] for p in placed)
|
||||
h0 = max(p[1] + p[3] for p in placed)
|
||||
return placed, w0, h0
|
||||
|
||||
|
||||
def _ic_q(v):
|
||||
""" Quantise a score for comparison — mirrors the JS round-trip.
|
||||
"""
|
||||
return int(math.floor(v * 1e9 + 0.5))
|
||||
|
||||
|
||||
def _ic_pack_sweep(sizes, gap):
|
||||
""" Best packing over candidate widths and placement orders.
|
||||
|
||||
Returns (placements, w0, h0) in source pixels, or None.
|
||||
"""
|
||||
used = sum(w * h for w, h in sizes)
|
||||
lo = max(w for w, h in sizes) + gap
|
||||
hi = sum(w for w, h in sizes) + gap * len(sizes)
|
||||
orders = [
|
||||
list(range(len(sizes))),
|
||||
sorted(range(len(sizes)), key=lambda i: (-sizes[i][1], i)),
|
||||
sorted(range(len(sizes)), key=lambda i: (-sizes[i][0], i)),
|
||||
sorted(range(len(sizes)), key=lambda i: (-sizes[i][0] * sizes[i][1], i)),
|
||||
]
|
||||
found = None
|
||||
for order in orders:
|
||||
ordered = [sizes[i] for i in order]
|
||||
best = None
|
||||
for step in range(_IC_PACK_WIDTH_STEPS):
|
||||
width = lo + (hi - lo) * step / (_IC_PACK_WIDTH_STEPS - 1)
|
||||
got = _ic_skyline_pack(ordered, width, gap)
|
||||
if got is None:
|
||||
continue
|
||||
placed, w0, h0 = got
|
||||
fill = used / float(w0 * h0)
|
||||
aspect = w0 / h0
|
||||
if not _IC_PACK_ASPECT_MIN <= aspect <= _IC_PACK_ASPECT_MAX:
|
||||
continue
|
||||
# Tightest wins; ties go to the squarer sheet, then wider.
|
||||
key = (-_ic_q(fill), _ic_q(abs(math.log(aspect))), -_ic_q(aspect))
|
||||
if best is None or key < best[0]:
|
||||
best = (key, fill, placed, w0, h0, order)
|
||||
if best is not None and (found is None or best[0] < found[0]):
|
||||
found = best
|
||||
if found is None:
|
||||
return None
|
||||
_, _fill, placed, w0, h0, order = found
|
||||
boxes = [None] * len(sizes)
|
||||
for slot, (x, y, w, h) in zip(order, placed):
|
||||
# noinspection PyTypeChecker
|
||||
boxes[slot] = (x, y, w, h)
|
||||
return boxes, w0, h0
|
||||
|
||||
|
||||
def _ic_align_down(v):
|
||||
return max(_ALIGN, int(v // _ALIGN) * _ALIGN)
|
||||
|
||||
|
||||
def _ic_align_up(v):
|
||||
return max(_ALIGN, int(math.ceil(v / float(_ALIGN))) * _ALIGN)
|
||||
|
||||
|
||||
def _ic_box(x, y, w, h, width, height):
|
||||
""" One integer box: SIZE rounded once, position rounded and clamped. """
|
||||
bw = max(1, min(width, int(math.floor(w + 0.5))))
|
||||
bh = max(1, min(height, int(math.floor(h + 0.5))))
|
||||
x0 = max(0, min(width - bw, int(math.floor(x + 0.5))))
|
||||
y0 = max(0, min(height - bh, int(math.floor(y + 0.5))))
|
||||
return x0, y0, bw, bh
|
||||
|
||||
|
||||
def _ic_plan_natural(sizes, budget, gap):
|
||||
""" Plan a natural-sizing sheet.
|
||||
|
||||
`sizes` is [(w, h), ...] in source pixels; `budget` the pixel budget
|
||||
(math.inf for no cap). Returns {"width", "height", "boxes"} with
|
||||
boxes as integer (x, y, w, h) in canvas pixels, or None.
|
||||
A frame of gap/2 is left around the whole sheet, matching the visual
|
||||
weight of the inter-layer gaps.
|
||||
"""
|
||||
found = _ic_pack_sweep(sizes, gap)
|
||||
if found is None:
|
||||
return None
|
||||
boxes, w0, h0 = found
|
||||
frame = int(round(gap / 2.0)) # half-gap frame; 0 when gap is 0
|
||||
if budget != math.inf:
|
||||
budget = max(1.0, budget - 4 * frame * frame)
|
||||
s_exact = min(1.0, math.sqrt(budget / float(w0 * h0)))
|
||||
if s_exact >= 1.0 and _ic_align_up(w0) * _ic_align_up(h0) <= budget:
|
||||
width = _ic_align_up(w0)
|
||||
height = _ic_align_up(h0)
|
||||
scale = 1.0
|
||||
else:
|
||||
width = _ic_align_down(s_exact * w0)
|
||||
height = max(_ALIGN, int(math.floor(
|
||||
(h0 * width / float(w0)) / _ALIGN + 0.5)) * _ALIGN)
|
||||
scale = min(width / float(w0), height / float(h0), 1.0)
|
||||
ox = (width - w0 * scale) / 2.0
|
||||
oy = (height - h0 * scale) / 2.0
|
||||
out = []
|
||||
for x, y, w, h in boxes:
|
||||
out.append(_ic_box(ox + x * scale, oy + y * scale, w * scale,
|
||||
h * scale, width, height))
|
||||
# Expand the canvas by the frame and shift every box inward by it.
|
||||
width += 2 * frame
|
||||
height += 2 * frame
|
||||
out = [(x + frame, y + frame, w, h) for x, y, w, h in out]
|
||||
return {"width": width, "height": height, "boxes": out}
|
||||
|
||||
|
||||
class ImageComposer:
|
||||
""" Compose multiple IMAGE inputs into one sheet, natural sizing. """
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
optional = {}
|
||||
for i in range(1, _IC_MAX_IMAGES + 1):
|
||||
optional[f"image{i}"] = ("IMAGE", {"tooltip":
|
||||
"Image layer — connect another Load Image node to reveal "
|
||||
"the next input slot."})
|
||||
return {"required": {
|
||||
"gap": ("INT", {"default": 0, "min": 0, "max": 256, "step": 2,
|
||||
"tooltip": "Pixels of background between layers."}),
|
||||
"background": (list(_IC_BACKGROUNDS), {"default": "black",
|
||||
"tooltip": "Colour behind the layers."}),
|
||||
"max_megapixels": ("FLOAT", {"default": 0.0,
|
||||
"min": 0.0, "max": 128.0, "step": 0.01,
|
||||
"tooltip": "Cap the sheet size (1.0 = 1024x1024 px). "
|
||||
"0 = no cap."}),
|
||||
},
|
||||
"optional": optional}
|
||||
|
||||
CATEGORY = "noEmbryo/Image"
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES = ("IMAGE",)
|
||||
FUNCTION = "compose"
|
||||
DESCRIPTION = (
|
||||
" Compose several images into ONE image. Images keep their order "
|
||||
" and relative pixel sizes (natural sizing, never enlarged) and are "
|
||||
" packed as tightly as possible; rows are chosen automatically. "
|
||||
" The preview refreshes instantly when an upstream image, crop, "
|
||||
" rotation or megapixel cap changes — no workflow run needed.")
|
||||
|
||||
# noinspection PyMethodMayBeStatic
|
||||
def compose(self, gap=8, background="black",
|
||||
max_megapixels=0.0, **kwargs):
|
||||
# Collect connected images, in input order.
|
||||
# KJNodes Set/Get nodes pass IMAGE tensors through graph links.
|
||||
# If they arrive as lists (e.g. after JSON round-trip), convert them.
|
||||
tiles = []
|
||||
for i in range(1, _IC_MAX_IMAGES + 1):
|
||||
t = kwargs.get(f"image{i}")
|
||||
if t is not None:
|
||||
if not isinstance(t, torch.Tensor):
|
||||
# Handle string (JSON-encoded tensor), dict-wrapped, lists
|
||||
if isinstance(t, str):
|
||||
try:
|
||||
t = json.loads(t)
|
||||
except (json.JSONDecodeError, ValueError):
|
||||
continue
|
||||
if isinstance(t, dict):
|
||||
t = t.get("image") or t.get("value") or t.get("data")
|
||||
# noinspection PyBroadException
|
||||
try:
|
||||
t = torch.tensor(t, dtype=torch.float32)
|
||||
except Exception:
|
||||
continue
|
||||
tiles.append(t[0] if t.dim() == 4 else t) # (H, W, C)
|
||||
if not tiles:
|
||||
raise ValueError("ImageComposer: no images connected. Connect at "
|
||||
"least one image input.")
|
||||
|
||||
gap = max(0, int(gap))
|
||||
try:
|
||||
mp = float(max_megapixels)
|
||||
except (TypeError, ValueError):
|
||||
mp = 0.0
|
||||
budget = max(1.0, mp * 1024.0 * 1024.0) if mp > 0 else math.inf
|
||||
|
||||
sizes = [(int(t.shape[1]), int(t.shape[0])) for t in tiles]
|
||||
plan = _ic_plan_natural(sizes, budget, gap)
|
||||
if plan is None:
|
||||
raise ValueError("ImageComposer: could not find a layout.")
|
||||
|
||||
width, height = plan["width"], plan["height"]
|
||||
fill = _IC_BACKGROUNDS.get(background, 0.0)
|
||||
canvas = torch.full((1, height, width, 3), fill, dtype=torch.float32)
|
||||
|
||||
for idx, (tile, (x, y, w, h)) in enumerate(zip(tiles, plan["boxes"])):
|
||||
th, tw = int(tile.shape[0]), int(tile.shape[1])
|
||||
# Fit the tile inside its slot, centered, never enlarging.
|
||||
scale = min(w / float(tw), h / float(th), 1.0)
|
||||
nw, nh = max(1, min(w, round(tw * scale))), max(1, min(h, round(th * scale)))
|
||||
px = x + (w - nw) // 2
|
||||
py = y + (h - nh) // 2
|
||||
tile = tile.permute(2, 0, 1).unsqueeze(0) # (1, C, H, W)
|
||||
scaled = torch.nn.functional.interpolate(
|
||||
tile, size=(nh, nw), mode="bilinear",
|
||||
antialias=True).squeeze(0).permute(1, 2, 0) # (H, W, C)
|
||||
canvas[:, py:py + nh, px:px + nw, :] = scaled.clamp(0.0, 1.0)
|
||||
|
||||
return (canvas,)
|
||||
|
||||
@classmethod
|
||||
def IS_CHANGED(cls, gap=8, background="black",
|
||||
max_megapixels=0.0, **kwargs):
|
||||
m = hashlib.sha256()
|
||||
m.update(str(gap).encode("utf-8"))
|
||||
m.update(str(background).encode("utf-8"))
|
||||
m.update(str(max_megapixels).encode("utf-8"))
|
||||
for i in range(1, _IC_MAX_IMAGES + 1):
|
||||
t = kwargs.get(f"image{i}")
|
||||
if t is not None:
|
||||
if not isinstance(t, torch.Tensor):
|
||||
t = torch.tensor(t, dtype=torch.float32)
|
||||
m.update(str(t.shape).encode("utf-8"))
|
||||
return m.digest().hex()
|
||||
|
||||
# noinspection PyUnusedLocal
|
||||
@classmethod
|
||||
def VALIDATE_INPUTS(cls, **_):
|
||||
return True
|
||||
|
||||
|
||||
# Middleware to handle clipspace file resolution
|
||||
@web.middleware
|
||||
async def clipspace_resolver_middleware(request, handler):
|
||||
+1310
File diff suppressed because it is too large
Load Diff
@@ -1,11 +1,14 @@
|
||||
import os, re, io
|
||||
import json
|
||||
import subprocess
|
||||
import tempfile
|
||||
from os.path import realpath, join, dirname, isabs, splitext, basename
|
||||
from datetime import datetime
|
||||
import folder_paths
|
||||
from .load_image_from_path import LoadImageFromPathEnhanced
|
||||
from .stitcher import (H3MotionContextClipStitcher, H3ContextLatentConverter,
|
||||
H3MotionContextClipPurge)
|
||||
from .image_nodes import LoadImageFromPathEnhanced, ImageComposer
|
||||
from .minimax import (H3MotionContextClipStitcher, H3ClipRefiner,
|
||||
H3ContextLatentConverter,
|
||||
H3MotionContextClipPurge, H3AVLatentFromVideo)
|
||||
|
||||
MANIFEST = {"name": "noEmbryo Nodes",
|
||||
"version": (1, 6, 6),
|
||||
@@ -77,7 +80,7 @@ class JsonPromptLoader:
|
||||
RETURN_TYPES = ("STRING",)
|
||||
RETURN_NAMES = ("Prompt",)
|
||||
FUNCTION = "run"
|
||||
CATEGORY = "noEmbryo"
|
||||
CATEGORY = "noEmbryo/Prompt"
|
||||
|
||||
def run(self, json_path, selected_item, variable, custom_prompt):
|
||||
self.load_data(json_path)
|
||||
@@ -244,7 +247,7 @@ class PromptTermList:
|
||||
RETURN_TYPES = ("STRING",)
|
||||
RETURN_NAMES = ("Term",)
|
||||
# OUTPUT_NODE = True
|
||||
CATEGORY = "noEmbryo/Term Nodes"
|
||||
CATEGORY = "noEmbryo/Prompt/Term Nodes"
|
||||
FUNCTION = "run"
|
||||
|
||||
def run(self, terms, strength, store_input, text=None):
|
||||
@@ -476,14 +479,216 @@ class AutoSaveWorkflow:
|
||||
return (status,)
|
||||
|
||||
|
||||
class ReplaceAudioNoReEncode:
|
||||
""" A minimal ComfyUI custom node that replaces the audio stream of an existing
|
||||
video file with a new audio track, using ffmpeg's stream-copy mode for the
|
||||
video (`-c:v copy`). The video bitstream is remuxed losslessly and is never
|
||||
decoded/re-encoded — only the container is rewritten with a new audio stream.
|
||||
|
||||
Requires ffmpeg to be installed and available on PATH.
|
||||
|
||||
video_path : path to an existing encoded video file (e.g. output of
|
||||
VHS Video Combine, or any .mp4/.mov/.mkv on disk).
|
||||
audio : standard ComfyUI AUDIO type ({"waveform": tensor, "sample_rate": int}),
|
||||
e.g. from Load Audio, VHS audio output, or a generated audio node.
|
||||
"""
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"video_path": ("STRING", {"default": "", "multiline": False,
|
||||
"tooltip": "Path to the video file whose audio stream "
|
||||
"will be replaced (e.g. any .mp4/.mov/.mkv on disk)."}),
|
||||
"filename_prefix": ("STRING", {"default": "audio_replaced",
|
||||
"tooltip": "Prefix for the output file name.\n"
|
||||
"The result is saved in the ComfyUI output "
|
||||
"directory as:\n"
|
||||
"<prefix>_<video name>_<counter>.<ext>"}),
|
||||
"audio_codec": (["aac", "copy"], {"default": "aac",
|
||||
"tooltip": "How to encode the new audio stream:\n"
|
||||
"• aac: re-encode to AAC 192kbps (always "
|
||||
"used when the audio comes from the AUDIO "
|
||||
"tensor input)\n"
|
||||
"• copy: remux the audio file losslessly, "
|
||||
"without re-encoding (only meaningful when "
|
||||
"using the audio_path input)"}),
|
||||
},
|
||||
"optional": {
|
||||
"audio": ("AUDIO", {"tooltip": "ComfyUI AUDIO signal (e.g. from Load Audio or a "
|
||||
"generated audio node) to use as the new audio "
|
||||
"stream.\nIgnored if audio_path is set."}),
|
||||
"audio_path": ("STRING", {"default": "", "multiline": False,
|
||||
"tooltip": "Path to an audio file — or a video file, whose "
|
||||
"audio stream will be extracted — to use as the new "
|
||||
"audio stream. If set, it takes priority over the "
|
||||
"audio tensor input."}),
|
||||
"shortest": ("BOOLEAN", {"default": True,
|
||||
"tooltip": "If enabled and the audio is shorter/longer than "
|
||||
"the video, the output is trimmed to the "
|
||||
"shorter of the two streams."}),
|
||||
},
|
||||
"hidden": {
|
||||
"prompt": "PROMPT",
|
||||
"extra_pnginfo": "EXTRA_PNGINFO",
|
||||
},
|
||||
}
|
||||
|
||||
DESCRIPTION = ("Replaces the audio stream of a video file without re-encoding the video. "
|
||||
"The new audio comes either from an AUDIO tensor input or from an audio file "
|
||||
"given by audio_path. Requires ffmpeg on the PATH.")
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
RETURN_NAMES = ("video_path",)
|
||||
OUTPUT_TOOLTIPS = ("The path of the output video file with the replaced audio stream.",)
|
||||
FUNCTION = "replace_audio"
|
||||
CATEGORY = "noEmbryo"
|
||||
OUTPUT_NODE = True
|
||||
|
||||
@staticmethod
|
||||
def _ffm_escape(text):
|
||||
""" Escapes a string for use as a value in an ffmetadata file """
|
||||
for ch in ("\\", "=", ";", "#", "\n"):
|
||||
text = text.replace(ch, "\\" + ch) if ch != "\n" else text.replace(ch, r"\n")
|
||||
return text
|
||||
|
||||
@staticmethod
|
||||
def write_wave_file(wave_path, waveform, sample_rate):
|
||||
""" Writes a waveform tensor to a wav file, using only the standard library
|
||||
"""
|
||||
import wave
|
||||
import numpy as np
|
||||
if waveform.dim() == 1: # [samples] -> [1, samples]
|
||||
waveform = waveform.unsqueeze(0)
|
||||
# [channels, samples] -> [samples, channels]
|
||||
samples = waveform.cpu().numpy().T
|
||||
samples = np.clip(samples, -1.0, 1.0)
|
||||
pcm = (samples * 32767.0).astype(np.int16)
|
||||
with wave.open(wave_path, "wb") as wf:
|
||||
wf.setnchannels(pcm.shape[1])
|
||||
wf.setsampwidth(2) # 2 bytes = 16 bit
|
||||
wf.setframerate(sample_rate)
|
||||
wf.writeframes(pcm.tobytes())
|
||||
|
||||
def replace_audio(self, video_path, filename_prefix, audio_codec,
|
||||
audio=None, audio_path="", shortest=True,
|
||||
prompt=None, extra_pnginfo=None):
|
||||
if not video_path or not os.path.isfile(video_path):
|
||||
raise FileNotFoundError(f"Video file not found: {video_path!r}")
|
||||
|
||||
output_dir = folder_paths.get_output_directory()
|
||||
os.makedirs(output_dir, exist_ok=True)
|
||||
|
||||
tmp_audio_path = None
|
||||
if audio_path:
|
||||
if not os.path.isfile(audio_path):
|
||||
raise FileNotFoundError(f"Audio file not found: {audio_path!r}")
|
||||
second_input = audio_path
|
||||
elif audio is not None:
|
||||
# --- Write the incoming AUDIO tensor to a temp wav file ---
|
||||
waveform = audio["waveform"]
|
||||
sample_rate = audio["sample_rate"]
|
||||
if waveform.dim() == 3: # [batch, channels, samples] -> take first item
|
||||
waveform = waveform[0]
|
||||
tmp_audio_fd, tmp_audio_path = tempfile.mkstemp(suffix=".wav")
|
||||
os.close(tmp_audio_fd)
|
||||
self.write_wave_file(tmp_audio_path, waveform, sample_rate)
|
||||
second_input = tmp_audio_path
|
||||
# Copying raw PCM into a container makes no sense, so force aac
|
||||
audio_codec = "aac"
|
||||
else:
|
||||
raise ValueError("No audio given: connect an AUDIO input or set audio_path.")
|
||||
|
||||
# --- Build a unique output path ---
|
||||
base_name = os.path.splitext(os.path.basename(video_path))[0]
|
||||
ext = os.path.splitext(video_path)[1] or ".mp4"
|
||||
# Start from max existing number + 1, so deleted files don't cause name reuse.
|
||||
# The prefix may contain subdirectories (e.g. "MMH3\NewAudio"), so the scan
|
||||
# must look in the directory the files are actually written to.
|
||||
out_path = os.path.join(output_dir, f"{filename_prefix}_{base_name}_001{ext}")
|
||||
scan_dir = os.path.dirname(out_path)
|
||||
os.makedirs(scan_dir, exist_ok=True)
|
||||
# listdir() returns bare filenames, so only the last component of the
|
||||
# prefix (without the directory part) can appear in them
|
||||
prefix_name = os.path.basename(filename_prefix.replace("\\", "/"))
|
||||
counter = 1
|
||||
pattern = re.compile(rf"^{re.escape(prefix_name)}_{re.escape(base_name)}"
|
||||
rf"_(\d+){re.escape(ext)}$")
|
||||
for fname in os.listdir(scan_dir):
|
||||
m = pattern.match(fname)
|
||||
if m:
|
||||
counter = max(counter, int(m.group(1)) + 1)
|
||||
out_name = f"{filename_prefix}_{base_name}_{counter:03d}{ext}"
|
||||
out_path = os.path.join(output_dir, out_name)
|
||||
|
||||
# --- Write the workflow metadata to a temp ffmetadata file ---
|
||||
# (avoids Windows command-line length limits that -metadata args would hit)
|
||||
meta_fd, meta_path = tempfile.mkstemp(suffix=".txt")
|
||||
os.close(meta_fd)
|
||||
with io.open(meta_path, "w", encoding="utf-8") as mf:
|
||||
mf.write(";FFMETADATA1\n")
|
||||
if prompt is not None:
|
||||
mf.write(f"prompt={self._ffm_escape(json.dumps(prompt))}\n")
|
||||
if extra_pnginfo and "workflow" in extra_pnginfo:
|
||||
mf.write(f"workflow={self._ffm_escape(json.dumps(extra_pnginfo['workflow']))}\n")
|
||||
|
||||
# --- ffmpeg: stream-copy the video, only touch the audio ---
|
||||
cmd = [
|
||||
"ffmpeg", "-y",
|
||||
"-i", video_path,
|
||||
"-i", second_input,
|
||||
"-i", meta_path,
|
||||
"-map", "0:v:0",
|
||||
"-map", "1:a:0",
|
||||
"-map_metadata", "2",
|
||||
"-c:v", "copy",
|
||||
]
|
||||
if audio_codec == "copy":
|
||||
cmd += ["-c:a", "copy"]
|
||||
else:
|
||||
cmd += ["-c:a", "aac", "-b:a", "192k"]
|
||||
# allow arbitrary metadata keys in these containers
|
||||
if ext.lower() in (".mp4", ".mov"):
|
||||
cmd += ["-movflags", "use_metadata_tags"]
|
||||
if shortest:
|
||||
cmd.append("-shortest")
|
||||
cmd.append(out_path)
|
||||
|
||||
def run_ffmpeg(command):
|
||||
return subprocess.run(command, capture_output=True, text=True)
|
||||
|
||||
try:
|
||||
result = run_ffmpeg(cmd)
|
||||
if result.returncode != 0 and audio_codec == "copy":
|
||||
# "copy" can fail when the source audio codec is incompatible with
|
||||
# the output container (e.g. PCM in an AVI -> mp4). Retry with aac.
|
||||
fallback_cmd = list(cmd)
|
||||
for i, arg in enumerate(fallback_cmd):
|
||||
if arg == "-c:a" and fallback_cmd[i + 1] == "copy":
|
||||
fallback_cmd[i + 1] = "aac"
|
||||
result = run_ffmpeg(fallback_cmd)
|
||||
if result.returncode != 0:
|
||||
raise RuntimeError(f"ffmpeg failed (exit {result.returncode}):\n{result.stderr}")
|
||||
finally:
|
||||
for tmp in (tmp_audio_path, meta_path):
|
||||
if tmp and os.path.exists(tmp):
|
||||
os.remove(tmp)
|
||||
|
||||
return (out_path,)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {f"JsonPromptLoader -{__author__}": JsonPromptLoader,
|
||||
f"Resolution Scale -{__author__}": ResolutionScale,
|
||||
f"Regex Text Chopper -{__author__}": RegExTextChopper,
|
||||
f"Auto Save Workflow -{__author__}": AutoSaveWorkflow,
|
||||
f"Load Image (from path) -{__author__}": LoadImageFromPathEnhanced,
|
||||
f"Image Composer -{__author__}": ImageComposer,
|
||||
f"H3MotionContextClipStitcher -{__author__}": H3MotionContextClipStitcher,
|
||||
f"H3ClipRefiner -{__author__}": H3ClipRefiner,
|
||||
f"H3MotionContextClipPurge -{__author__}": H3MotionContextClipPurge,
|
||||
f"H3ContextLatentConverter -{__author__}": H3ContextLatentConverter,
|
||||
f"H3AVLatentFromVideo -{__author__}": H3AVLatentFromVideo,
|
||||
f"ReplaceAudioNoReEncode -{__author__}": ReplaceAudioNoReEncode,
|
||||
"PromptTermList1": PromptTermList1,
|
||||
"PromptTermList2": PromptTermList2,
|
||||
"PromptTermList3": PromptTermList3,
|
||||
@@ -497,9 +702,13 @@ NODE_DISPLAY_NAME_MAPPINGS = {f"JsonPromptLoader -{__author__}": f"Json Prompt L
|
||||
f"Regex Text Chopper -{__author__}": f"Regex Text Chopper /{__author__}",
|
||||
f"Auto Save Workflow -{__author__}": f"Auto Save Workflow /{__author__}",
|
||||
f"Load Image (from path) -{__author__}": f"Load Image (from path) /{__author__}",
|
||||
f"Image Composer -{__author__}": f"Image Composer /{__author__}",
|
||||
f"H3MotionContextClipStitcher -{__author__}": f"H3 Motion Context Clip Stitcher /{__author__}",
|
||||
f"H3ClipRefiner -{__author__}": f"H3 Clip Refiner /{__author__}",
|
||||
f"H3MotionContextClipPurge -{__author__}": f"H3 Motion Context Clip Purge /{__author__}",
|
||||
f"H3ContextLatentConverter -{__author__}": f"H3 Context Latent Converter /{__author__}",
|
||||
f"H3AVLatentFromVideo -{__author__}": f"H3 AV Latent from Video /{__author__}",
|
||||
f"ReplaceAudioNoReEncode -{__author__}": f"Replace Audio no ReEncode /{__author__}",
|
||||
"PromptTermList1": f"PromptTermList 1 /{__author__}",
|
||||
"PromptTermList2": f"PromptTermList 2 /{__author__}",
|
||||
"PromptTermList3": f"PromptTermList 3 /{__author__}",
|
||||
|
||||
+6
-5
@@ -1,5 +1,5 @@
|
||||
[project]
|
||||
name = "comfyui-noembryo"
|
||||
name = "comfyui-noembryo" # Unique identifier used in registry URLs (lowercase, no spaces)
|
||||
description = """
|
||||
A collection of nodes for ComyUI. \n
|
||||
* "Load Image (from path)" lets you load an image from any path in your computer or a URL, and use a selection rectangle at the preview to crop it. It can also
|
||||
@@ -12,14 +12,15 @@ limit the output's size in megapixels. \n
|
||||
* "PromptTermList (1-6)" nodes to help with the creation of Prompts. \n
|
||||
* "Auto Save Workflow" can save the current workflow to a .json file automatically. \n
|
||||
"""
|
||||
version = "1.6.6"
|
||||
version = "1.6.7"
|
||||
license = {text = "MIT License"}
|
||||
dependencies = []
|
||||
|
||||
[project.urls]
|
||||
Repository = "https://github.com/noembryo/ComfyUI-noEmbryo"
|
||||
# Used by Comfy Registry https://comfyregistry.org
|
||||
|
||||
[tool.comfy]
|
||||
PublisherId = "noembryo"
|
||||
DisplayName = "noEmbryoNodes"
|
||||
Icon = "https://iili.io/JmSdmAJ.png"
|
||||
PublisherId = "noembryo" # Obtained from your Comfy Registry account
|
||||
DisplayName = "noEmbryoNodes" # The name displayed in the UI
|
||||
Icon = "https://iili.io/JmSdmAJ.png" # (Optional) URL to an SVG/PNG icon
|
||||
|
||||
-673
@@ -1,673 +0,0 @@
|
||||
"""H3 Motion Context clip stitcher for ComfyUI.
|
||||
|
||||
Loads NikoDemon80/ComfyUI-H3-Motion-Context clip archive files (h3_motion_context_av_v1),
|
||||
decodes each approved clip once, crossfades the carried Motion Context head from
|
||||
clips, and concatenates the picture/audio into one IMAGE + AUDIO pair.
|
||||
|
||||
This intentionally does NOT reconstruct a NestedTensor and feed the saved files back
|
||||
into Motion Context.
|
||||
The archive format is the sampler output, and this node is a final-media assembly tool.
|
||||
"""
|
||||
|
||||
import fnmatch
|
||||
import glob
|
||||
import logging
|
||||
import os
|
||||
import re
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
import folder_paths
|
||||
from comfy.utils import ProgressBar
|
||||
|
||||
try:
|
||||
from comfy_execution.graph_utils import get_original_node_id
|
||||
except Exception:
|
||||
get_original_node_id = None
|
||||
|
||||
try:
|
||||
from safetensors.torch import load_file as st_load
|
||||
except Exception:
|
||||
st_load = None
|
||||
|
||||
try:
|
||||
import torchaudio
|
||||
except Exception:
|
||||
torchaudio = None
|
||||
|
||||
log_ = logging.getLogger("h3_motion_context_clip_stitcher")
|
||||
|
||||
|
||||
def _resolve_folder(path):
|
||||
p = (path or "").strip().strip('"').strip("'")
|
||||
if not p:
|
||||
p = "h3_context"
|
||||
candidates = [p, os.path.join(folder_paths.get_output_directory(), p)]
|
||||
for c in candidates:
|
||||
if os.path.isdir(c):
|
||||
return os.path.abspath(c)
|
||||
raise FileNotFoundError("H3 Motion Context Clip Stitcher: folder not found: %s\n"
|
||||
"You can use an absolute path or a path relative to "
|
||||
"ComfyUI's output folder." % p)
|
||||
|
||||
|
||||
def _clip_number(path):
|
||||
name = os.path.basename(path)
|
||||
# noinspection RegExpUnnecessaryNonCapturingGroup
|
||||
pat = re.compile(r"(?:^|_)(\d{5})(?:\.safetensors)$", re.IGNORECASE)
|
||||
m = pat.search(name)
|
||||
return int(m.group(1)) if m else -1
|
||||
|
||||
|
||||
def _find_files(folder, pattern, first_clip, last_clip):
|
||||
pattern = (pattern or "clip_*.safetensors").strip()
|
||||
paths = []
|
||||
for p in glob.glob(os.path.join(folder, pattern)):
|
||||
if not os.path.isfile(p):
|
||||
continue
|
||||
if not p.lower().endswith(".safetensors"):
|
||||
continue
|
||||
idx = _clip_number(p)
|
||||
if idx < 0:
|
||||
continue
|
||||
if idx < int(first_clip):
|
||||
continue
|
||||
if 0 < int(last_clip) < idx:
|
||||
continue
|
||||
paths.append((idx, p))
|
||||
paths.sort(key=lambda x: x[0])
|
||||
if not paths:
|
||||
raise FileNotFoundError("H3 Motion Context Clip Stitcher: no numbered "
|
||||
".safetensors files matched '%s' in %s."
|
||||
% (pattern, folder))
|
||||
|
||||
# Do not silently skip a missing numbered clip. A gap usually means an
|
||||
# approved clip was not saved, and silently stitching around it would make
|
||||
# a misleading final timeline.
|
||||
expected = paths[0][0]
|
||||
for idx, _ in paths:
|
||||
if idx != expected:
|
||||
raise ValueError("H3 Motion Context Clip Stitcher: missing clip %05d between "
|
||||
"the selected archive files." % expected)
|
||||
expected += 1
|
||||
return paths
|
||||
|
||||
|
||||
def _load_archive(path):
|
||||
if st_load is None:
|
||||
raise RuntimeError("safetensors is unavailable in this "
|
||||
"ComfyUI Python environment.")
|
||||
# noinspection PyCallingNonCallable
|
||||
data = st_load(path, device="cpu")
|
||||
if "video" not in data or "audio" not in data:
|
||||
raise ValueError("%s is not an h3_motion_context_av_v1 archive: "
|
||||
"expected 'video' and 'audio'." % path)
|
||||
video = data["video"]
|
||||
audio = data["audio"]
|
||||
if video.ndim != 5:
|
||||
raise ValueError("%s: expected video [B,C,T,H,W], got %s"
|
||||
% (path, tuple(video.shape)))
|
||||
if audio.ndim != 4:
|
||||
raise ValueError("%s: expected audio [B,C,2,T], got %s"
|
||||
% (path, tuple(audio.shape)))
|
||||
if video.shape[0] != 1 or audio.shape[0] != 1:
|
||||
raise ValueError("%s: only batch size 1 archive clips are supported." % path)
|
||||
return video, audio
|
||||
|
||||
|
||||
def _decode_video(vae, video_latent):
|
||||
""" Decode the H3 video stream and normalize to ComfyUI IMAGE format.
|
||||
"""
|
||||
images = vae.decode(video_latent)
|
||||
# H3's VAE normally returns [B,T,H,W,C]. Some VAE implementations can
|
||||
# return [T,H,W,C], so accept both.
|
||||
if images.ndim == 5:
|
||||
images = images.reshape(-1, *images.shape[-3:])
|
||||
elif images.ndim != 4:
|
||||
raise RuntimeError("H3 video VAE returned unexpected shape %s"
|
||||
% (tuple(images.shape),))
|
||||
return images.to(torch.float32).clamp(0, 1).cpu()
|
||||
|
||||
|
||||
def _decode_audio(audio_vae, audio_latent):
|
||||
""" Decode the H3 audio stream using the same convention as ComfyUI's VAEDecodeAudio.
|
||||
"""
|
||||
audio = audio_vae.decode(audio_latent)
|
||||
# Current ComfyUI audio VAE returns [B,L,C]. Convert to [B,C,L].
|
||||
if audio.ndim != 3:
|
||||
raise RuntimeError("H3 audio VAE returned unexpected shape %s" % (tuple(images.shape),))
|
||||
audio = audio.movedim(-1, 1)
|
||||
sr = int(getattr(audio_vae, "audio_sample_rate_output",
|
||||
getattr(audio_vae, "audio_sample_rate", 32000)))
|
||||
return {"waveform": audio.to(torch.float32).cpu(), "sample_rate": sr}
|
||||
|
||||
|
||||
def _resample_audio(audio, target_sr):
|
||||
if audio is None:
|
||||
return None
|
||||
sr = int(audio["sample_rate"])
|
||||
if sr == int(target_sr):
|
||||
return audio
|
||||
if torchaudio is None:
|
||||
raise RuntimeError("Audio sample rates differ (%d vs %d), but torchaudio is "
|
||||
"unavailable to resample them." % (sr, int(target_sr)))
|
||||
# noinspection PyUnresolvedReferences
|
||||
waveform = torchaudio.functional.resample(audio["waveform"], sr, int(target_sr))
|
||||
return {"waveform": waveform, "sample_rate": int(target_sr)}
|
||||
|
||||
|
||||
def _crossfade_boundary(prev_tail_images, cur_images, prev_tail_wave, cur_wave,
|
||||
overlap_frames, cross_samples):
|
||||
""" Crossfade the previous clip's tail with the current clip's head.
|
||||
|
||||
prev_tail_images: [L,H,W,C] cur_images: [T,H,W,C]
|
||||
prev_tail_wave : [1,C,Ls] cur_wave: [1,C,Cs] (or None)
|
||||
Returns (blend_images [L,H,W,C], blend_wave [1,C,Ls] or None).
|
||||
|
||||
Video uses a linear dissolve ramp; audio uses an equal-power (cos/sin)
|
||||
ramp over the same time window so picture and sound stay in sync.
|
||||
"""
|
||||
L = int(overlap_frames)
|
||||
if L <= 0:
|
||||
return cur_images[:0], None
|
||||
if L == 1:
|
||||
alpha = torch.full((1, 1, 1, 1), 0.5, dtype=prev_tail_images.dtype,
|
||||
device=prev_tail_images.device)
|
||||
else:
|
||||
alpha = torch.linspace(0.0, 1.0, L, dtype=prev_tail_images.dtype,
|
||||
device=prev_tail_images.device).view(L, 1, 1, 1)
|
||||
blend_images = prev_tail_images * (1.0 - alpha) + cur_images[:L] * alpha
|
||||
|
||||
blend_wave = None
|
||||
if prev_tail_wave is not None and cur_wave is not None:
|
||||
n = int(cross_samples)
|
||||
if n <= 0:
|
||||
blend_wave = prev_tail_wave
|
||||
else:
|
||||
n = min(n, int(prev_tail_wave.shape[-1]), int(cur_wave.shape[-1]))
|
||||
theta = torch.linspace(0.0, 1.5707963267948966, n, dtype=prev_tail_wave.dtype,
|
||||
device=prev_tail_wave.device).view(1, 1, n)
|
||||
blend_wave = (prev_tail_wave[..., :n] * torch.cos(theta)
|
||||
+ cur_wave[..., :n] * torch.sin(theta))
|
||||
return blend_images, blend_wave
|
||||
|
||||
|
||||
def _av_from_live_latent(latent):
|
||||
""" Extract (video, audio) tensors from an in-memory H3 AV LATENT,
|
||||
using the same unpacking convention as NikoDemon80's own
|
||||
_streams_from_latent()/save(): latent["samples"] is a NestedTensor
|
||||
(or tuple/list) whose unbind() gives (video, audio) in that order.
|
||||
"""
|
||||
if not isinstance(latent, dict) or "samples" not in latent:
|
||||
raise ValueError("h3_motion_context: expected a MiniMax H3 AV latent dict with "
|
||||
"a 'samples' key, got %r" % type(latent))
|
||||
samples = latent["samples"]
|
||||
if hasattr(samples, "unbind"):
|
||||
parts = list(samples.unbind())
|
||||
elif isinstance(samples, (tuple, list)):
|
||||
parts = list(samples)
|
||||
else:
|
||||
raise ValueError("h3_motion_context: expected a MiniMax H3 AV latent (a nested "
|
||||
"video/audio pair), got %r" % type(samples))
|
||||
if len(parts) < 2:
|
||||
raise ValueError("h3_motion_context: latent has no audio stream; wire the "
|
||||
"sampler output of an H3 AV graph.")
|
||||
# NestedTensor.unbind() returns views into the packed underlying storage.
|
||||
# Passing such views (or tensors still carrying nested metadata) to a VAE's
|
||||
# CUDA kernels can trigger cudaErrorIllegalAddress. Force a real, dense,
|
||||
# detached CPU copy of each stream before handing them to the VAE.
|
||||
video = parts[0].detach().to("cpu", copy=True).contiguous()
|
||||
audio = parts[1].detach().to("cpu", copy=True).contiguous()
|
||||
# Live streams can carry the same shapes as the archive files (video
|
||||
# [B,C,T,H,W] or [C,T,H,W]; audio [B,C,2,T] or [B,L,C]).
|
||||
expected_ndim = {"video": (4, 5), "audio": (3, 4)}
|
||||
for name, t in (("video", video), ("audio", audio)):
|
||||
if t.ndim not in expected_ndim[name]:
|
||||
raise ValueError("h3_motion_context: live %s stream has unexpected "
|
||||
"shape %s." % (name, tuple(t.shape)))
|
||||
if not torch.is_floating_point(t):
|
||||
raise ValueError("h3_motion_context: live %s stream is not a float "
|
||||
"tensor (dtype %s)." % (name, t.dtype))
|
||||
return video, audio
|
||||
|
||||
|
||||
class H3MotionContextClipStitcher:
|
||||
""" Load, decode, and crossfade approved H3 Motion Context clips.
|
||||
"""
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {"required": {"folder": ("STRING", {"default": "h3_context",
|
||||
"tooltip": "Folder containing clip_00001.safetensors, "
|
||||
"clip_00002.safetensors, etc.\nAbsolute paths and paths relative "
|
||||
"to ComfyUI/output are accepted."}),
|
||||
"pattern": ("STRING", {"default": "clip_*.safetensors",
|
||||
"tooltip": "Filename glob. The final five-digit number is treated as "
|
||||
"the clip index."}),
|
||||
"first_clip": ("INT", {"default": 1, "min": 1, "max": 9999,
|
||||
"tooltip": "First approved clip to include."}),
|
||||
"last_clip": ("INT", {"default": 0, "min": 0, "max": 9999,
|
||||
"tooltip": "Last clip to include. 0 = every clip from first_clip onward."}),
|
||||
"context_length": (["5", "22", "39", "56"], {"default": "22",
|
||||
"tooltip": "Number of decoded frames to crossfade at each clip boundary. "
|
||||
"The normal setting is 22 frames.\n"
|
||||
"This is the overlap length that is dissolved between "
|
||||
"adjacent clips.\n"
|
||||
"5, 22, 39 or 56 are the lengths that are a whole number of "
|
||||
"latent steps, which is why other numbers aren't offered."}),
|
||||
"fps": ("FLOAT", {"default": 24.0, "min": 1.0, "max": 240.0, "step": 0.001,
|
||||
"tooltip": "H3 native output rate. Keep this at 24 unless your workflow "
|
||||
"deliberately changes it."}), },
|
||||
"optional": {"video_vae": ("VAE", {"tooltip": "MiniMax H3 video VAE "
|
||||
"(FP16 or INT8 ConvRot)."}),
|
||||
"audio_vae": ("VAE", {
|
||||
"tooltip": "MiniMax H3 audio VAE FP32. Required for the AUDIO "
|
||||
"output."}),
|
||||
"latent": ("LATENT", {
|
||||
"tooltip": "Optional: the currently-generated AV latent (from your "
|
||||
"H3 sampler), used in place of the highest-numbered file "
|
||||
"on disk."}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE", "AUDIO", "INT", "STRING")
|
||||
RETURN_NAMES = ("images", "audio", "frame_count", "report")
|
||||
FUNCTION = "stitch"
|
||||
CATEGORY = "noEmbryo"
|
||||
DESCRIPTION = ("Final assembly for NikoDemon80's H3 Motion Context AV clip archives.\n"
|
||||
"Loads numbered h3_motion_context_av_v1 files, decodes one clip at a "
|
||||
"time, dissolves the overlap between adjacent clips (video + synchronized audio), "
|
||||
"and concatenates them to a final video and audio stream.")
|
||||
|
||||
# noinspection PyUnusedLocal
|
||||
@classmethod
|
||||
def IS_CHANGED(cls, folder, pattern, first_clip, last_clip, context_length, fps,
|
||||
video_vae=None, audio_vae=None, latent=None):
|
||||
# noinspection PyBroadException
|
||||
try:
|
||||
d = _resolve_folder(folder)
|
||||
files = _find_files(d, pattern, first_clip, last_clip)
|
||||
# noinspection PyTypeChecker
|
||||
return tuple((p, os.stat(p).st_mtime_ns, os.path.getsize(p))
|
||||
for _, p in files) + (int(context_length), float(fps),)
|
||||
except Exception:
|
||||
return float("NaN")
|
||||
|
||||
@staticmethod
|
||||
def stitch(folder, pattern, first_clip, last_clip, context_length, fps,
|
||||
video_vae=None, audio_vae=None, latent=None,):
|
||||
if video_vae is None:
|
||||
raise ValueError("Connect your MiniMax H3 video VAE to 'video_vae'.")
|
||||
if st_load is None:
|
||||
raise RuntimeError("safetensors is not available in this ComfyUI environment")
|
||||
|
||||
d = _resolve_folder(folder)
|
||||
files = _find_files(d, pattern, first_clip, last_clip)
|
||||
live_entry = None
|
||||
|
||||
if latent is not None:
|
||||
if files:
|
||||
files = files[:-1] # drop the presumed-duplicate on-disk file
|
||||
live_index = files[-1][0] + 1 if files else int(first_clip)
|
||||
else:
|
||||
live_index = int(first_clip)
|
||||
video_latent, audio_latent = _av_from_live_latent(latent)
|
||||
live_entry = (live_index, None, video_latent, audio_latent) # path=None marks it as live
|
||||
|
||||
image_parts = []
|
||||
audio_parts = []
|
||||
report_lines = []
|
||||
target_sr = None
|
||||
|
||||
overlap = int(context_length)
|
||||
|
||||
prev_tail_img = None
|
||||
prev_tail_wave = None
|
||||
|
||||
all_entries = [(idx, path, None, None) for idx, path in files]
|
||||
if live_entry is not None:
|
||||
# noinspection PyTypeChecker
|
||||
all_entries.append(live_entry)
|
||||
|
||||
total_count = len(files) + (1 if live_entry is not None else 0)
|
||||
# noinspection PyCallingNonCallable
|
||||
pbar = ProgressBar(total_count, node_id=get_original_node_id()
|
||||
if get_original_node_id is not None else None)
|
||||
log_.info("H3 clip stitcher: %d clip(s) selected from %s", total_count, d)
|
||||
|
||||
# Degenerate crossfade (no overlap or a single clip) falls back to a
|
||||
# plain concatenation, which is exactly what the trim modes would do.
|
||||
crossfade_active = overlap > 0 and len(all_entries) > 1
|
||||
|
||||
for pos, (idx, path, live_video, live_audio) in enumerate(all_entries):
|
||||
if path is not None:
|
||||
video_latent, audio_latent = _load_archive(path)
|
||||
else:
|
||||
video_latent, audio_latent = live_video, live_audio
|
||||
log_.info("H3 clip stitcher: clip %05d taken from live latent input",
|
||||
idx)
|
||||
|
||||
# Decode one clip at a time. The decoded result is immediately moved
|
||||
# to CPU, so a long chain does not keep every VAE result on VRAM.
|
||||
images = _decode_video(video_vae, video_latent)
|
||||
del video_latent
|
||||
|
||||
audio = None
|
||||
if audio_vae is not None:
|
||||
audio = _decode_audio(audio_vae, audio_latent,
|
||||
# normalize=normalize_audio_per_clip
|
||||
)
|
||||
del audio_latent
|
||||
|
||||
decoded_frames = int(images.shape[0])
|
||||
is_last = pos == len(all_entries) - 1
|
||||
|
||||
if not crossfade_active:
|
||||
# Single clip (or zero overlap): no boundaries to blend, just
|
||||
# emit the whole decoded clip and finish.
|
||||
if audio is not None and target_sr is None:
|
||||
target_sr = int(audio["sample_rate"])
|
||||
image_parts.append(images)
|
||||
if audio is not None:
|
||||
audio_parts.append(audio["waveform"])
|
||||
report_lines.append("clip_%05d: decoded=%d frames, no crossfade "
|
||||
"(single clip), audio=%.4fs"
|
||||
% (idx, decoded_frames, 0.0
|
||||
if audio is None else audio["waveform"].shape[-1]
|
||||
/ float(audio["sample_rate"])))
|
||||
pbar.update_absolute(pos + 1, total_count)
|
||||
del images
|
||||
if audio is not None:
|
||||
del audio
|
||||
continue
|
||||
|
||||
if crossfade_active:
|
||||
if decoded_frames < 2 * overlap:
|
||||
raise ValueError("Crossfade requires each clip to have at least "
|
||||
"2*context_length (%d) frames; clip %05d has %d."
|
||||
% (overlap, idx, decoded_frames))
|
||||
|
||||
# Resample this clip's audio to the shared target rate before
|
||||
# splitting, so the head/tail sample counts line up across clips.
|
||||
if audio is not None:
|
||||
if target_sr is None:
|
||||
target_sr = int(audio["sample_rate"])
|
||||
audio = _resample_audio(audio, target_sr)
|
||||
if prev_tail_wave is not None:
|
||||
prev_tail_wave = _resample_audio(prev_tail_wave, target_sr)
|
||||
|
||||
n = 0
|
||||
if audio is not None:
|
||||
sr = int(audio["sample_rate"])
|
||||
n = int(round((overlap / float(fps)) * sr))
|
||||
if n <= 0:
|
||||
n = 1
|
||||
if n >= audio["waveform"].shape[-1]:
|
||||
raise ValueError("Audio is too short to extract a %d-frame "
|
||||
"(%0.4fs) crossfade head/tail for clip %05d."
|
||||
% (overlap, overlap / float(fps), idx))
|
||||
|
||||
head_img = images[:overlap]
|
||||
body_img = images[overlap:-overlap]
|
||||
tail_img = images[-overlap:]
|
||||
|
||||
head_wave = body_wave = tail_wave = None
|
||||
if audio is not None:
|
||||
wave = audio["waveform"]
|
||||
sr = int(audio["sample_rate"])
|
||||
head_wave = {"waveform": wave[..., :n], "sample_rate": sr}
|
||||
body_wave = {"waveform": wave[..., n:-n], "sample_rate": sr}
|
||||
tail_wave = {"waveform": wave[..., -n:], "sample_rate": sr}
|
||||
|
||||
if pos == 0:
|
||||
# First clip: emit head+body raw, buffer the tail for the next boundary.
|
||||
image_parts.append(torch.cat([head_img, body_img], dim=0))
|
||||
if audio is not None:
|
||||
audio_parts.append(torch.cat([head_wave["waveform"],
|
||||
body_wave["waveform"]], dim=-1))
|
||||
prev_tail_img = tail_img
|
||||
prev_tail_wave = tail_wave
|
||||
else:
|
||||
blend_img, blend_wave = _crossfade_boundary(prev_tail_img, images,
|
||||
prev_tail_wave[
|
||||
"waveform"] if prev_tail_wave is not None else None,
|
||||
audio["waveform"] if audio is not None else None, overlap, n)
|
||||
image_parts.append(blend_img)
|
||||
if audio is not None:
|
||||
audio_parts.append(blend_wave)
|
||||
audio_parts.append(body_wave["waveform"])
|
||||
if is_last:
|
||||
# Last clip: emit body+tail raw after its boundary blend.
|
||||
image_parts.append(torch.cat([body_img, tail_img], dim=0))
|
||||
if audio is not None:
|
||||
audio_parts.append(tail_wave["waveform"])
|
||||
else:
|
||||
image_parts.append(body_img)
|
||||
prev_tail_img = tail_img
|
||||
prev_tail_wave = tail_wave
|
||||
|
||||
kept_frames = decoded_frames - (overlap if not is_last else 0)
|
||||
audio_sec = (0.0 if audio is None else
|
||||
audio["waveform"].shape[-1] / float(audio["sample_rate"]))
|
||||
report_lines.append("clip_%05d: decoded=%d frames, crossfade=%d frames "
|
||||
"(%.4fs), kept=%d, audio=%.4fs"
|
||||
% (idx, decoded_frames, overlap, overlap / float(fps),
|
||||
kept_frames, audio_sec))
|
||||
|
||||
# Advance the green progress bar once this clip is fully decoded and
|
||||
# its parts have been appended to the stitched timeline.
|
||||
pbar.update_absolute(pos + 1, total_count)
|
||||
|
||||
del images
|
||||
if audio is not None:
|
||||
del audio
|
||||
|
||||
final_images = torch.cat(image_parts, dim=0).contiguous()
|
||||
del image_parts
|
||||
|
||||
final_audio = None
|
||||
if audio_parts:
|
||||
final_waveform = torch.cat(audio_parts, dim=-1).contiguous()
|
||||
del audio_parts
|
||||
final_audio = {"waveform": final_waveform, "sample_rate": int(target_sr)}
|
||||
|
||||
frame_count = int(final_images.shape[0])
|
||||
video_seconds = frame_count / float(fps)
|
||||
audio_seconds = (final_audio["waveform"].shape[-1]
|
||||
/ float(final_audio["sample_rate"])
|
||||
if final_audio is not None else 0.0)
|
||||
|
||||
report_lines.append("TOTAL: %d frames = %.4fs at %.3f fps; audio=%.4fs%s"
|
||||
% (frame_count, video_seconds, float(fps), audio_seconds,
|
||||
"" if final_audio is not None
|
||||
else " (no audio_vae connected)"))
|
||||
report = "\n".join(report_lines)
|
||||
log_.info("H3 clip stitcher finished: %d frames (%.3fs), audio %.3fs",
|
||||
frame_count, video_seconds, audio_seconds)
|
||||
|
||||
return final_images, final_audio, frame_count, report
|
||||
|
||||
|
||||
class _AVStreamPair:
|
||||
"""Minimal stand-in for a NestedTensor: wraps (video, audio) tensors and
|
||||
exposes the unbind() interface that comfy-core's LTXVSeparateAVLatent
|
||||
(and the H3 sampler code) expects. The wrapped tensors are always dense,
|
||||
detached, contiguous copies, so they are safe to feed to the VAE kernels.
|
||||
"""
|
||||
|
||||
def __init__(self, video, audio):
|
||||
self._parts = [video, audio]
|
||||
|
||||
def unbind(self):
|
||||
# noinspection PyTypeChecker
|
||||
return tuple(self._parts)
|
||||
|
||||
def __iter__(self):
|
||||
return iter(self._parts)
|
||||
|
||||
def __len__(self):
|
||||
return len(self._parts)
|
||||
|
||||
|
||||
class H3ContextLatentConverter:
|
||||
""" Convert an H3 Motion Context archive latent (as loaded by
|
||||
MiniMaxH3MotionContextLoadLatent, whose 'samples' is a plain list) into
|
||||
the AV latent form that comfy-core's LTXVSeparateAVLatent expects
|
||||
(av_latent["samples"].unbind() -> (video, audio)).
|
||||
"""
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {"required": {"latent": ("LATENT", {
|
||||
"tooltip": "An H3 AV latent, e.g. the output of "
|
||||
"MiniMaxH3MotionContextLoadLatent. Its 'samples' must be a "
|
||||
"NestedTensor or a (video, audio) pair."})}}
|
||||
|
||||
RETURN_TYPES = ("LATENT",)
|
||||
RETURN_NAMES = ("latent",)
|
||||
FUNCTION = "convert"
|
||||
CATEGORY = "noEmbryo"
|
||||
DESCRIPTION = ("Repackages the AV latent loaded from an H3 Motion Context clip "
|
||||
"archive into the nested (video, audio) form that "
|
||||
"LTXVSeparateAVLatent expects, so saved clips can be re-sampled, "
|
||||
"upscaled, or re-saved.")
|
||||
|
||||
@staticmethod
|
||||
def convert(latent):
|
||||
if not isinstance(latent, dict) or "samples" not in latent:
|
||||
raise ValueError("h3_context_latent_converter: expected a latent dict with "
|
||||
"a 'samples' key, got %r" % type(latent))
|
||||
|
||||
out = dict(latent)
|
||||
samples = latent["samples"]
|
||||
|
||||
if hasattr(samples, "unbind"):
|
||||
parts = list(samples.unbind())
|
||||
elif isinstance(samples, (tuple, list)):
|
||||
parts = list(samples)
|
||||
else:
|
||||
raise ValueError("h3_context_latent_converter: 'samples' is neither "
|
||||
"unbindable nor a (video, audio) pair, got %r"
|
||||
% type(samples))
|
||||
|
||||
if len(parts) < 2:
|
||||
raise ValueError("h3_context_latent_converter: latent has no audio "
|
||||
"stream (only %d part(s)); expected an H3 AV latent."
|
||||
% len(parts))
|
||||
|
||||
expected_ndim = {"video": (4, 5), "audio": (3, 4)}
|
||||
names = ("video", "audio")
|
||||
dense = []
|
||||
for name, t in zip(names, parts[:2]):
|
||||
if t.ndim not in expected_ndim[name]:
|
||||
raise ValueError("h3_context_latent_converter: %s stream has "
|
||||
"unexpected shape %s." % (name, tuple(t.shape)))
|
||||
if not torch.is_floating_point(t):
|
||||
raise ValueError("h3_context_latent_converter: %s stream is not a "
|
||||
"float tensor (dtype %s)." % (name, t.dtype))
|
||||
# Force a real, dense, detached CPU copy: views into packed storage
|
||||
# (or tensors still carrying nested metadata) can make VAE CUDA
|
||||
# kernels crash with cudaErrorIllegalAddress.
|
||||
dense.append(t.detach().to("cpu", copy=True).contiguous())
|
||||
|
||||
converted = {k: v for k, v in out.items() if k != "samples"}
|
||||
converted["samples"] = _AVStreamPair(dense[0], dense[1])
|
||||
return (converted,)
|
||||
|
||||
|
||||
class H3MotionContextClipPurge:
|
||||
""" Delete the saved H3 Motion Context clip archive files from a folder.
|
||||
"""
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {"required": {"mode": ("BOOLEAN", {"default": True,
|
||||
"label_on": "Purge", "label_off": "Preview (dry run)",
|
||||
"tooltip": "Purge (Enabled): delete the matching files.\n"
|
||||
"Preview (dry run, Disabled): delete nothing; the report "
|
||||
"just lists the files that would be deleted."}),
|
||||
"folder": ("STRING", {"default": "h3_context",
|
||||
"tooltip": "Folder whose root-level clip archives will be deleted.\n"
|
||||
"Absolute paths and paths relative to ComfyUI/output are "
|
||||
"accepted."}),
|
||||
"pattern": ("STRING", {"default": "clip_*.safetensors",
|
||||
"tooltip": "Filename glob. Only root-level FILES matching this "
|
||||
"pattern are deleted.\nSub-folders are never touched."}), },
|
||||
"hidden": {"mode": "BOOLEAN"}}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
RETURN_NAMES = ("report",)
|
||||
FUNCTION = "purge"
|
||||
CATEGORY = "noEmbryo"
|
||||
OUTPUT_NODE = True
|
||||
DESCRIPTION = ("Deletes the numbered h3_motion_context_av_v1 clip archive files "
|
||||
"at the root of a folder (default: h3_context).\n"
|
||||
"Purge (Enabled): deletes the files.\n"
|
||||
"Preview (Disabled): dry run - the report only lists what would "
|
||||
"be deleted.\nOnly files matching the pattern are removed; "
|
||||
"sub-folders and everything inside them are left untouched.")
|
||||
|
||||
# noinspection PyUnusedLocal
|
||||
@classmethod
|
||||
def IS_CHANGED(cls, mode, folder, pattern):
|
||||
return float("NaN")
|
||||
|
||||
@staticmethod
|
||||
def purge(mode, folder, pattern):
|
||||
d = _resolve_folder(folder)
|
||||
pattern = (pattern or "clip_*.safetensors").strip()
|
||||
|
||||
doomed = []
|
||||
for entry in os.scandir(d):
|
||||
if entry.is_file(follow_symlinks=False) and not entry.is_dir():
|
||||
if fnmatch.fnmatch(entry.name, pattern):
|
||||
doomed.append((entry.name, entry.stat().st_size))
|
||||
|
||||
if not mode: # Preview (dry run)
|
||||
lines = ["H3 clip purge (DRY RUN) in %s - nothing was deleted:" % d]
|
||||
lines += [" would delete: %s (%s)" % (name, _fmt_size(size))
|
||||
for name, size in doomed] or [" no matching files."]
|
||||
lines.append("TOTAL: %d file(s), %s" %
|
||||
(len(doomed), _fmt_size(sum(s for _, s in doomed))))
|
||||
report = "\n".join(lines)
|
||||
log_.info(report)
|
||||
return (report,)
|
||||
|
||||
deleted = 0
|
||||
freed = 0
|
||||
lines = ["H3 clip purge in %s:" % d]
|
||||
for name, size in doomed:
|
||||
try:
|
||||
os.remove(os.path.join(d, name))
|
||||
deleted += 1
|
||||
freed += size
|
||||
lines.append(" deleted: %s (%s)" % (name, _fmt_size(size)))
|
||||
except OSError as e:
|
||||
lines.append(" FAILED to delete %s: %s" % (name, e))
|
||||
if not deleted and not doomed:
|
||||
lines.append(" no matching files.")
|
||||
lines.append("TOTAL: deleted %d file(s), freed %s" %
|
||||
(deleted, _fmt_size(freed)))
|
||||
report = "\n".join(lines)
|
||||
log_.info(report)
|
||||
return (report,)
|
||||
|
||||
|
||||
def _fmt_size(num_bytes):
|
||||
size = float(num_bytes)
|
||||
for unit in ("B", "KiB", "MiB", "GiB"):
|
||||
if size < 1024.0:
|
||||
return "%.1f %s" % (size, unit)
|
||||
size /= 1024.0
|
||||
return "%.1f TiB" % size
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"H3MotionContextClipStitcher": H3MotionContextClipStitcher,
|
||||
"H3ContextLatentConverter": H3ContextLatentConverter,
|
||||
"H3MotionContextClipPurge": H3MotionContextClipPurge,
|
||||
}
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"H3MotionContextClipStitcher": "H3 Motion Context Clip Stitcher",
|
||||
"H3ContextLatentConverter": "H3 Context Latent Converter",
|
||||
"H3MotionContextClipPurge": "H3 Motion Context Clip Purge",
|
||||
}
|
||||
@@ -6,6 +6,35 @@ import {api} from "../../scripts/api.js";
|
||||
// Store last browsed path
|
||||
let lastBrowsedPath = '';
|
||||
|
||||
// Registry of ImageComposer nodes for global graph change notifications
|
||||
const composerNodes = new Set();
|
||||
|
||||
// Global graph change listener — fires when ANY connection changes in the graph.
|
||||
// This catches upstream bypasses (e.g. disconnecting a loader from a KJ Set node)
|
||||
// that don't trigger the Composer's own onConnectionsChange.
|
||||
let graphChangeHandlerInstalled = false;
|
||||
function installGraphChangeListener() {
|
||||
if (graphChangeHandlerInstalled) return;
|
||||
graphChangeHandlerInstalled = true;
|
||||
// ComfyUI's LGraphCanvas fires "graphchange" on the canvas when connections change.
|
||||
// We hook into the canvas to catch all connection changes.
|
||||
const canvas = app.canvas;
|
||||
if (canvas) {
|
||||
const prevOnGraphChange = canvas.onGraphChange;
|
||||
canvas.onGraphChange = function () {
|
||||
const r = prevOnGraphChange?.apply(this, arguments);
|
||||
// Notify all Composer nodes to refresh thumbnails
|
||||
for (const node of composerNodes) {
|
||||
if (node.refreshThumbs) {
|
||||
node.refreshThumbs();
|
||||
node.setDirtyCanvas?.(true, true);
|
||||
}
|
||||
}
|
||||
return r;
|
||||
};
|
||||
}
|
||||
}
|
||||
|
||||
/** Return the directory of a path string (handles Windows/Unix + [input]/[output]/[temp] suffixes). */
|
||||
function dirnameOf(pathStr) {
|
||||
if (!pathStr || typeof pathStr !== 'string') return '';
|
||||
@@ -554,6 +583,762 @@ const RESIZE_ZONE = 15;
|
||||
const PREVIEW_TOOLTIP =
|
||||
"Drag to crop · Drag inside to move · Drag corners to resize · Click outside selection to clear · Click ↻ to rotate 90°";
|
||||
|
||||
// ---------------------------------------------------------------------------
|
||||
// Image Composer — growing IMAGE inputs and a live arrangement preview.
|
||||
// Mirrors the backend's natural-mode skyline packing (image_nodes.py).
|
||||
// ---------------------------------------------------------------------------
|
||||
|
||||
const IC_MAX_IMAGES = 16;
|
||||
const IC_ALIGN = 16;
|
||||
const IC_PACK_ASPECT_MIN = 0.45;
|
||||
const IC_PACK_ASPECT_MAX = 2.2;
|
||||
const IC_PACK_WIDTH_STEPS = 48;
|
||||
const IC_EPS = 1e-9;
|
||||
const IC_BACKGROUNDS = { black: "#000", grey: "#808080", white: "#fff" };
|
||||
|
||||
// Direct port of the backend skyline packer.
|
||||
function icSkylinePack(sizes, width, gap) {
|
||||
const sky = [[0, width, 0]];
|
||||
const placed = [];
|
||||
for (const [w, h] of sizes) {
|
||||
const iw = w + gap, ih = h + gap;
|
||||
if (iw > width + IC_EPS) return null;
|
||||
let best = null;
|
||||
for (let i = 0; i < sky.length; i++) {
|
||||
const start = sky[i][0];
|
||||
if (start + iw > width + IC_EPS) continue;
|
||||
let y = 0, span = iw, j = i;
|
||||
while (span > IC_EPS && j < sky.length) {
|
||||
if (sky[j][2] > y) y = sky[j][2];
|
||||
span -= sky[j][1];
|
||||
j++;
|
||||
}
|
||||
if (span > IC_EPS) continue;
|
||||
if (best === null || y < best[0] || (y === best[0] && start < best[1]))
|
||||
best = [y, start];
|
||||
}
|
||||
if (best === null) return null;
|
||||
const [y, x] = best;
|
||||
placed.push([x, y, w, h]);
|
||||
const cut = [], end = x + iw;
|
||||
for (const [sx, sw, sy] of sky) {
|
||||
if (sx + sw <= x + IC_EPS || sx >= end - IC_EPS) { cut.push([sx, sw, sy]); continue; }
|
||||
if (sx < x) cut.push([sx, x - sx, sy]);
|
||||
if (sx + sw > end) cut.push([end, sx + sw - end, sy]);
|
||||
}
|
||||
cut.push([x, iw, y + ih]);
|
||||
cut.sort((a, b) => a[0] - b[0]);
|
||||
const merged = [];
|
||||
for (const seg of cut) {
|
||||
if (merged.length && Math.abs(merged[merged.length - 1][2] - seg[2]) < IC_EPS)
|
||||
merged[merged.length - 1][1] += seg[1];
|
||||
else merged.push([...seg]);
|
||||
}
|
||||
sky.length = 0;
|
||||
sky.push(...merged);
|
||||
}
|
||||
const w0 = Math.max(...placed.map((p) => p[0] + p[2]));
|
||||
const h0 = Math.max(...placed.map((p) => p[1] + p[3]));
|
||||
return [placed, w0, h0];
|
||||
}
|
||||
|
||||
function icPackSweep(sizes, gap) {
|
||||
const used = sizes.reduce((s, [w, h]) => s + w * h, 0);
|
||||
const lo = Math.max(...sizes.map((s) => s[0])) + gap;
|
||||
const hi = sizes.reduce((s, [w]) => s + w, 0) + gap * sizes.length;
|
||||
const idx = sizes.map((_, i) => i);
|
||||
const orders = [
|
||||
idx,
|
||||
[...idx].sort((a, b) => sizes[b][1] - sizes[a][1] || a - b),
|
||||
[...idx].sort((a, b) => sizes[b][0] - sizes[a][0] || a - b),
|
||||
[...idx].sort((a, b) =>
|
||||
sizes[b][0] * sizes[b][1] - sizes[a][0] * sizes[a][1] || a - b),
|
||||
];
|
||||
// Quantized score for exact backend parity.
|
||||
const q = (v) => Math.floor(v * 1e9 + 0.5);
|
||||
let found = null;
|
||||
for (const order of orders) {
|
||||
const ordered = order.map((i) => sizes[i]);
|
||||
let best = null;
|
||||
for (let step = 0; step < IC_PACK_WIDTH_STEPS; step++) {
|
||||
const width = lo + ((hi - lo) * step) / (IC_PACK_WIDTH_STEPS - 1);
|
||||
const got = icSkylinePack(ordered, width, gap);
|
||||
if (!got) continue;
|
||||
const [placed, w0, h0] = got;
|
||||
const fill = used / (w0 * h0);
|
||||
const aspect = w0 / h0;
|
||||
if (aspect < IC_PACK_ASPECT_MIN || aspect > IC_PACK_ASPECT_MAX) continue;
|
||||
const key = [-q(fill), q(Math.abs(Math.log(aspect))), -q(aspect)];
|
||||
if (best === null || icKeyLess(key, best.key)) {
|
||||
best = { key, placed, w0, h0, order };
|
||||
}
|
||||
}
|
||||
if (best && (!found || icKeyLess(best.key, found.key))) found = best;
|
||||
}
|
||||
if (!found) return null;
|
||||
const boxes = new Array(sizes.length).fill(null);
|
||||
found.order.forEach((slot, i) => { boxes[slot] = found.placed[i]; });
|
||||
return { boxes, w0: found.w0, h0: found.h0 };
|
||||
}
|
||||
|
||||
function icKeyLess(a, b) {
|
||||
for (let i = 0; i < a.length; i++) {
|
||||
if (a[i] !== b[i]) return a[i] < b[i];
|
||||
}
|
||||
return false;
|
||||
}
|
||||
|
||||
// Mirror of the backend's _ic_plan_natural (integer canvas, shared scale <= 1).
|
||||
// Includes the half-gap frame around the sheet, as the backend does.
|
||||
function icPlanNatural(sizes, gap) {
|
||||
const packed = icPackSweep(sizes, gap);
|
||||
if (!packed) return null;
|
||||
const { boxes, w0, h0 } = packed;
|
||||
const alignUp = (v) => Math.max(IC_ALIGN, Math.ceil(v / IC_ALIGN) * IC_ALIGN);
|
||||
// Frame of gap/2 around the whole sheet; 0 when gap is 0.
|
||||
const frame = Math.round(gap / 2);
|
||||
let width = alignUp(w0);
|
||||
let height = alignUp(h0);
|
||||
const out = boxes.map(([x, y, w, h]) => {
|
||||
const bw = Math.max(1, Math.round(w));
|
||||
const bh = Math.max(1, Math.round(h));
|
||||
return [Math.round(x), Math.round(y), bw, bh];
|
||||
});
|
||||
// Expand the canvas by the frame and shift every box inward by it.
|
||||
width += 2 * frame;
|
||||
height += 2 * frame;
|
||||
for (const b of out) {
|
||||
b[0] += frame;
|
||||
b[1] += frame;
|
||||
}
|
||||
return { width, height, boxes: out };
|
||||
}
|
||||
|
||||
app.registerExtension({
|
||||
name: "noEmbryo.ImageComposer",
|
||||
beforeRegisterNodeDef(nodeType, nodeData) {
|
||||
if (nodeData.name !== "Image Composer -noEmbryo") return;
|
||||
|
||||
const onNodeCreated = nodeType.prototype.onNodeCreated;
|
||||
nodeType.prototype.onNodeCreated = function () {
|
||||
const result = onNodeCreated
|
||||
? onNodeCreated.apply(this, arguments)
|
||||
: undefined;
|
||||
const node = this;
|
||||
|
||||
const mpWidget = node.widgets.find((w) => w.name === "max_megapixels");
|
||||
const gapWidget = node.widgets.find((w) => w.name === "gap");
|
||||
const bgWidget = node.widgets.find((w) => w.name === "background");
|
||||
|
||||
// Hide the managed widget (canvas + Nodes 2.0).
|
||||
for (const w of [mpWidget]) {
|
||||
if (w) {
|
||||
w.hidden = true;
|
||||
w.options = w.options || {};
|
||||
w.options.hidden = true;
|
||||
}
|
||||
}
|
||||
|
||||
const state = { thumbs: new Map(), box: null };
|
||||
|
||||
// Register this Composer node for global graph change notifications
|
||||
composerNodes.add(node);
|
||||
// Expose refreshThumbs on the node so the global listener can call it
|
||||
node.refreshThumbs = refreshThumbs;
|
||||
// Clean up registry when node is removed
|
||||
const prevOnRemoved = node.onRemoved;
|
||||
node.onRemoved = function () {
|
||||
composerNodes.delete(node);
|
||||
return prevOnRemoved?.apply(this, arguments);
|
||||
};
|
||||
// Install global graph change listener (once)
|
||||
installGraphChangeListener();
|
||||
|
||||
function connectedSlots() {
|
||||
const slots = [];
|
||||
for (let i = 1; i <= IC_MAX_IMAGES; i++) {
|
||||
const input = node.inputs?.find((inp) => inp.name === `image${i}`);
|
||||
if (input && input.link != null) slots.push(i);
|
||||
}
|
||||
return slots;
|
||||
}
|
||||
|
||||
// Return only slots that have a valid upstream image path
|
||||
// (not bypassed, not cleared). Used for preview packing to avoid
|
||||
// showing numbered placeholders for disabled/bypassed GetNodes.
|
||||
function validSlots() {
|
||||
return connectedSlots().filter((i) => {
|
||||
const info = upstreamPath(i);
|
||||
return info && info.path;
|
||||
});
|
||||
}
|
||||
|
||||
// --- Growing inputs -----------------------------------------
|
||||
// Keep exactly one trailing free slot: enough connected inputs
|
||||
// to hold every link, plus one empty one to grow into.
|
||||
function syncInputs() {
|
||||
let connected = 0;
|
||||
for (const inp of node.inputs || []) {
|
||||
if (inp.link != null) connected++;
|
||||
}
|
||||
const want = Math.min(IC_MAX_IMAGES, connected + 1);
|
||||
// Remove trailing unconnected inputs beyond the wanted count.
|
||||
while (node.inputs.length > want &&
|
||||
node.inputs[node.inputs.length - 1].link == null) {
|
||||
node.removeInput(node.inputs.length - 1);
|
||||
}
|
||||
// Add free slots until we reach the wanted count.
|
||||
let n = node.inputs.length;
|
||||
while (n < want) {
|
||||
n++;
|
||||
node.addInput(`image${n}`, "IMAGE");
|
||||
}
|
||||
}
|
||||
|
||||
const prevOnConn = nodeType.prototype.onConnectionsChange;
|
||||
nodeType.prototype.onConnectionsChange = function (side, slot, connect) {
|
||||
const r = prevOnConn?.apply(this, arguments);
|
||||
if (side === 1) {
|
||||
syncInputs();
|
||||
refreshThumbs();
|
||||
if (!connect) {
|
||||
// Connection was broken — clean up thumbnail entries
|
||||
// for any inputs that are no longer connected so the
|
||||
// Composer doesn't keep showing the bypassed image.
|
||||
let cleaned = false;
|
||||
for (const [key, entry] of state.thumbs) {
|
||||
const i = Number(key);
|
||||
const inp = node.inputs?.find((w) => w.name === `image${i}`);
|
||||
if (!inp || inp.link == null) {
|
||||
state.thumbs.delete(key);
|
||||
cleaned = true;
|
||||
}
|
||||
}
|
||||
if (cleaned) node.setDirtyCanvas?.(true, true);
|
||||
}
|
||||
}
|
||||
return r;
|
||||
};
|
||||
|
||||
// --- Thumbnail loading via the serve proxy -------------------
|
||||
function upstreamPath(slotIdx) {
|
||||
const input = node.inputs?.find((inp) => inp.name === `image${slotIdx}`);
|
||||
if (!input || input.link == null) return null;
|
||||
const link = app.graph.links[input.link];
|
||||
if (!link) return null;
|
||||
const src = app.graph._nodes_by_id?.[link.origin_id];
|
||||
if (!src) return null;
|
||||
|
||||
console.log(`[ImageComposer] slot ${slotIdx}: src type=${src.type || "?"} ` +
|
||||
`widgets=${(src.widgets || []).map(w => w.name).join(",")}`);
|
||||
|
||||
// Direct connection: LoadImageFromPathEnhanced
|
||||
const result = icExtractFromNode(src);
|
||||
if (result) {
|
||||
console.log(`[ImageComposer] slot ${slotIdx}: direct match path=${result.path}`);
|
||||
return result;
|
||||
}
|
||||
|
||||
// Intermediate nodes (e.g. KJ Set/Get): trace back
|
||||
const traced = icTraceBack(src);
|
||||
if (traced) {
|
||||
console.log(`[ImageComposer] slot ${slotIdx}: traced path=${traced.path}`);
|
||||
} else {
|
||||
console.log(`[ImageComposer] slot ${slotIdx}: no trace result, ` +
|
||||
`checking widgets for paths...`);
|
||||
const fallbackPath = icFindPathInWidgets(src);
|
||||
if (fallbackPath) {
|
||||
console.log(`[ImageComposer] slot ${slotIdx}: fallback path=${fallbackPath}`);
|
||||
return { path: fallbackPath, rotation: 0, crop: null, maxMp: 0,
|
||||
srcNode: src };
|
||||
}
|
||||
}
|
||||
return traced;
|
||||
}
|
||||
|
||||
// Extract path/crop/maxMp from a LoadImageFromPathEnhanced node.
|
||||
function icExtractFromNode(srcNode) {
|
||||
// If the source node is bypassed (mode 4), treat as no valid source.
|
||||
if (srcNode.mode === 4) return null;
|
||||
const pathW = srcNode.widgets?.find((w) => w.name === "image");
|
||||
const cropW = srcNode.widgets?.find((w) => w.name === "crop");
|
||||
if (!pathW) return null;
|
||||
let crop = null, rotation = 0;
|
||||
try {
|
||||
const data = JSON.parse(cropW?.value || "{}") || {};
|
||||
rotation = parseInt(data.rotation, 10) || 0;
|
||||
if (data.w > 0 && data.h > 0)
|
||||
crop = { x: +data.x, y: +data.y, w: +data.w, h: +data.h };
|
||||
} catch (e) { /* ignore */ }
|
||||
// The upstream megapixel cap shapes the tensor the backend
|
||||
// receives, so it must shape the packing too.
|
||||
const mpW = srcNode.widgets?.find((w) => w.name === "max_megapixels");
|
||||
const maxMp = Math.max(0, parseFloat(mpW?.value) || 0);
|
||||
return { path: String(pathW.value || "").trim(), rotation, crop,
|
||||
maxMp, srcNode: srcNode };
|
||||
}
|
||||
|
||||
// Generic fallback: check ALL widgets on a node for any string
|
||||
// that looks like a file path or URL.
|
||||
function icFindPathInWidgets(srcNode) {
|
||||
for (const w of srcNode.widgets || []) {
|
||||
const v = String(w.value || "").trim();
|
||||
if (!v) continue;
|
||||
if (v.startsWith("/") || v.startsWith("http") ||
|
||||
v.endsWith(".png") || v.endsWith(".jpg") ||
|
||||
v.endsWith(".jpeg") || v.endsWith(".webp") ||
|
||||
v.endsWith(".bmp") || v.endsWith(".gif")) {
|
||||
return v;
|
||||
}
|
||||
}
|
||||
return null;
|
||||
}
|
||||
|
||||
// Trace back through intermediate nodes to find the original
|
||||
// LoadImageFromPathEnhanced source.
|
||||
function icTraceBack(node) {
|
||||
// Strategy 1: follow input links backward through the graph
|
||||
for (const inp of node.inputs || []) {
|
||||
if (inp.link != null) {
|
||||
const l = app.graph.links[inp.link];
|
||||
if (l) {
|
||||
const src = app.graph._nodes_by_id?.[l.origin_id];
|
||||
if (src) {
|
||||
const result = icExtractFromNode(src);
|
||||
if (result) return result;
|
||||
const recursive = icTraceBack(src);
|
||||
if (recursive) return recursive;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// Strategy 2: KJ GetNode — match key to find SetNode's source
|
||||
const nodeType = node.type || "";
|
||||
if (nodeType === "GetNode" || nodeType.includes("Get")) {
|
||||
const kjResult = icTraceThroughKJ(node);
|
||||
if (kjResult) return kjResult;
|
||||
}
|
||||
|
||||
// Strategy 3: any widget on this node contains a path
|
||||
const path = icFindPathInWidgets(node);
|
||||
if (path) {
|
||||
return { path, rotation: 0, crop: null, maxMp: 0,
|
||||
srcNode: node };
|
||||
}
|
||||
|
||||
return null;
|
||||
}
|
||||
|
||||
// For a GetNode, find the matching SetNode by key,
|
||||
// then trace to the node that feeds the SetNode's input.
|
||||
function icTraceThroughKJ(getNode) {
|
||||
// KJ nodes store the key in widgets[0] (first widget).
|
||||
const keyW = getNode.widgets?.[0];
|
||||
if (!keyW) return null;
|
||||
const key = String(keyW.value ?? "");
|
||||
if (!key) return null;
|
||||
|
||||
// Search for a SetNode with matching key
|
||||
for (const nodeId in app.graph._nodes_by_id) {
|
||||
const n = app.graph._nodes_by_id[nodeId];
|
||||
if (n === getNode) continue;
|
||||
if (n.type !== "SetNode" && !n.type.includes("Set")) continue;
|
||||
// Found a SetNode — check if its key matches
|
||||
const setKeyW = n.widgets?.[0];
|
||||
if (!setKeyW) continue;
|
||||
if (String(setKeyW.value ?? "") !== key) continue;
|
||||
// If SetNode is bypassed (mode 4) or its input is disconnected,
|
||||
// the loader is effectively bypassed — don't return stale value.
|
||||
if (n.mode === 4) continue;
|
||||
if (!(n.inputs?.[0]?.link != null)) continue;
|
||||
// Key matches — follow SetNode's input (slot 0) to find source
|
||||
for (const inp of n.inputs || []) {
|
||||
if (inp.link != null) {
|
||||
const l = app.graph.links[inp.link];
|
||||
if (l) {
|
||||
const src = app.graph._nodes_by_id?.[l.origin_id];
|
||||
if (src) {
|
||||
const result = icExtractFromNode(src);
|
||||
if (result) return result;
|
||||
const recursive = icTraceBack(src);
|
||||
if (recursive) return recursive;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
return null;
|
||||
}
|
||||
|
||||
function loadThumb(slotIdx, entry) {
|
||||
entry.seq = (entry.seq || 0) + 1;
|
||||
const seq = entry.seq;
|
||||
const p = entry.path;
|
||||
if (!p) { entry.img = null; node.setDirtyCanvas?.(true, true); return; }
|
||||
const url = /^https?:\/\//i.test(p)
|
||||
? p
|
||||
: `/noembryo/serve_image?path=${encodeURIComponent(p)}` +
|
||||
`&t=${Date.now()}`;
|
||||
const img = new Image();
|
||||
img.onload = () => {
|
||||
if (entry.seq !== seq) return;
|
||||
// Backend order: ROTATE the full image first, THEN crop —
|
||||
// the crop coords are drawn on the rotated preview, so
|
||||
// they only map correctly onto the rotated image.
|
||||
let result = icRotate(img, entry.rotation);
|
||||
const c = entry.crop;
|
||||
if (c && c.w > 0 && c.h > 0) {
|
||||
const rw = result.width, rh = result.height;
|
||||
const cw = Math.max(1, Math.round(c.w * rw));
|
||||
const ch = Math.max(1, Math.round(c.h * rh));
|
||||
const cx = Math.max(0, Math.min(rw - 1,
|
||||
Math.round(c.x * rw)));
|
||||
const cy = Math.max(0, Math.min(rh - 1,
|
||||
Math.round(c.y * rh)));
|
||||
const cc = document.createElement("canvas");
|
||||
cc.width = cw;
|
||||
cc.height = ch;
|
||||
cc.getContext("2d").drawImage(result, cx, cy, cw, ch,
|
||||
0, 0, cw, ch);
|
||||
result = cc;
|
||||
}
|
||||
// Apply the upstream megapixel cap (downscale-only,
|
||||
// aspect-preserved — mirrors the backend behaviour).
|
||||
const mp = entry.maxMp;
|
||||
if (mp > 0) {
|
||||
const maxPixels = mp * 1024 * 1024;
|
||||
const cur = result.width * result.height;
|
||||
if (cur > maxPixels) {
|
||||
const sc = Math.sqrt(maxPixels / cur);
|
||||
const sc2 = document.createElement("canvas");
|
||||
sc2.width = Math.max(1, Math.round(result.width * sc));
|
||||
sc2.height = Math.max(1, Math.round(result.height * sc));
|
||||
sc2.getContext("2d").drawImage(
|
||||
result, 0, 0, sc2.width, sc2.height);
|
||||
result = sc2;
|
||||
}
|
||||
}
|
||||
entry.img = result;
|
||||
node.setDirtyCanvas?.(true, true);
|
||||
};
|
||||
img.onerror = () => {
|
||||
if (entry.seq !== seq) return;
|
||||
entry.img = null;
|
||||
node.setDirtyCanvas?.(true, true);
|
||||
};
|
||||
img.src = url;
|
||||
}
|
||||
|
||||
function icRotate(src, deg) {
|
||||
const d = ((deg % 360) + 360) % 360;
|
||||
if (!d) return src;
|
||||
const c = document.createElement("canvas");
|
||||
const quarter = (d / 90) % 4;
|
||||
if (quarter % 2 === 1) { c.width = src.height; c.height = src.width; }
|
||||
else { c.width = src.width; c.height = src.height; }
|
||||
const ctx = c.getContext("2d");
|
||||
ctx.translate(c.width / 2, c.height / 2);
|
||||
ctx.rotate((d * Math.PI) / 180);
|
||||
ctx.drawImage(src, -src.width / 2, -src.height / 2);
|
||||
return c;
|
||||
}
|
||||
|
||||
function refreshThumbs() {
|
||||
for (const i of connectedSlots()) {
|
||||
const info = upstreamPath(i);
|
||||
const entry = state.thumbs.get(i) || {};
|
||||
state.thumbs.set(i, entry);
|
||||
if (info && info.path) {
|
||||
const cropKey = `${info.crop ? JSON.stringify(info.crop) : ""}` +
|
||||
`|${info.maxMp}`;
|
||||
if (entry.path !== info.path ||
|
||||
entry.rotation !== info.rotation ||
|
||||
entry.cropKey !== cropKey) {
|
||||
entry.path = info.path;
|
||||
entry.rotation = info.rotation;
|
||||
entry.crop = info.crop;
|
||||
entry.maxMp = info.maxMp;
|
||||
entry.cropKey = cropKey;
|
||||
loadThumb(i, entry);
|
||||
}
|
||||
} else if (!info) {
|
||||
state.thumbs.delete(i);
|
||||
} else if (!info.path) {
|
||||
// Upstream exists but path is empty (loader cleared).
|
||||
// Drop the stale thumbnail so the Composer doesn't
|
||||
// keep showing the last received image.
|
||||
if (entry && entry.path) {
|
||||
entry.path = "";
|
||||
entry.img = null;
|
||||
entry.rotation = 0;
|
||||
entry.crop = null;
|
||||
entry.maxMp = 0;
|
||||
entry.cropKey = "";
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// --- Live preview widget ------------------------------------
|
||||
let allocHeight;
|
||||
const MIN_PREVIEW_H = 80;
|
||||
const MARGIN = 10;
|
||||
|
||||
function boxHeight(widget, widgetY, fallback) {
|
||||
const nodeH = node.size?.[1];
|
||||
const visible = node.widgets?.filter((w) => !w.hidden);
|
||||
const isLast = !!visible && visible[visible.length - 1] === widget;
|
||||
if (nodeH == null || widgetY == null || !isLast) return fallback;
|
||||
return Math.max(MIN_PREVIEW_H, nodeH - widgetY);
|
||||
}
|
||||
|
||||
const isVueMode = () =>
|
||||
typeof LiteGraph !== "undefined" && !!LiteGraph.vueNodesMode;
|
||||
|
||||
const preview = {
|
||||
name: "composer_preview",
|
||||
type: "noembryo_composer_preview",
|
||||
value: "",
|
||||
serialize: false,
|
||||
options: { serialize: false },
|
||||
computeLayoutSize() {
|
||||
return { minHeight: MIN_PREVIEW_H, maxHeight: 100000, minWidth: 0 };
|
||||
},
|
||||
draw(ctx, _node, widgetWidth, y, H, lowQuality) {
|
||||
const h = boxHeight(this, y, allocHeight ?? H) - 8;
|
||||
const x = MARGIN;
|
||||
const nodeW = _node?.size?.[0];
|
||||
const effWidth =
|
||||
!isVueMode() && nodeW ? Math.min(widgetWidth, nodeW) : widgetWidth;
|
||||
const w = effWidth - MARGIN * 2;
|
||||
const slots = validSlots();
|
||||
|
||||
// Gather sizes for the packing (thumbs may still be loading —
|
||||
// fall back to 1:1 aspect so the layout is stable).
|
||||
const sizes = slots.map((i) => {
|
||||
const t = state.thumbs.get(i);
|
||||
return t?.img ? [t.img.width, t.img.height] : [64, 64];
|
||||
});
|
||||
const gap = Math.max(0, parseInt(gapWidget?.value, 10) || 0);
|
||||
const plan = slots.length ? icPlanNatural(sizes, gap) : null;
|
||||
|
||||
state.box = null;
|
||||
ctx.save();
|
||||
ctx.fillStyle = "#00000033";
|
||||
ctx.fillRect(x, y, w, h);
|
||||
|
||||
if (!slots.length || !plan) {
|
||||
ctx.fillStyle = "#888";
|
||||
ctx.font = "12px sans-serif";
|
||||
ctx.textAlign = "center";
|
||||
ctx.textBaseline = "middle";
|
||||
ctx.fillText("Connect image inputs", x + w / 2, y + h / 2);
|
||||
ctx.restore();
|
||||
return;
|
||||
}
|
||||
|
||||
// Fit the plan inside the preview area, letterboxed.
|
||||
const areaH = h - 4;
|
||||
const s = Math.min(w / plan.width, areaH / plan.height);
|
||||
const pw = plan.width * s, ph = plan.height * s;
|
||||
const px0 = x + (w - pw) / 2, py0 = y + 2 + (areaH - ph) / 2;
|
||||
state.box = { px0, py0, pw, ph, s, plan, slots };
|
||||
|
||||
ctx.fillStyle = IC_BACKGROUNDS[bgWidget?.value] || "#000";
|
||||
ctx.fillRect(px0, py0, pw, ph);
|
||||
|
||||
slots.forEach((slotIdx, i) => {
|
||||
const [bx, by, bw, bh] = plan.boxes[i];
|
||||
const t = state.thumbs.get(slotIdx);
|
||||
const drawX = px0 + bx * s, drawY = py0 + by * s;
|
||||
// background for slots whose thumb hasn't loaded
|
||||
if (!t?.img) {
|
||||
ctx.fillStyle = "#333";
|
||||
ctx.fillRect(drawX, drawY, bw * s, bh * s);
|
||||
ctx.fillStyle = "#888";
|
||||
ctx.font = "10px sans-serif";
|
||||
ctx.textAlign = "center";
|
||||
ctx.textBaseline = "middle";
|
||||
ctx.fillText(`${slotIdx}`, drawX + (bw * s) / 2,
|
||||
drawY + (bh * s) / 2);
|
||||
return;
|
||||
}
|
||||
// Fit inside the slot, never enlarge (natural sizing).
|
||||
const scale = Math.min((bw * s) / t.img.width,
|
||||
(bh * s) / t.img.height, 1);
|
||||
const tw = t.img.width * scale, th = t.img.height * scale;
|
||||
ctx.drawImage(t.img, drawX, drawY, tw, th);
|
||||
});
|
||||
|
||||
// Sheet size pill
|
||||
ctx.fillStyle = "rgba(0,0,0,0.6)";
|
||||
ctx.font = "10px sans-serif";
|
||||
ctx.textAlign = "left";
|
||||
ctx.textBaseline = "alphabetic";
|
||||
const label = `${plan.width} x ${plan.height} px`;
|
||||
const tw = ctx.measureText(label).width;
|
||||
ctx.fillRect(x + 2, y + h - 16, tw + 8, 14);
|
||||
ctx.fillStyle = "#ddd";
|
||||
ctx.fillText(label, x + 6, y + h - 5);
|
||||
ctx.restore();
|
||||
},
|
||||
};
|
||||
|
||||
Object.defineProperty(preview, "computedHeight", {
|
||||
configurable: true,
|
||||
get() { return undefined; },
|
||||
set(v) { allocHeight = v; },
|
||||
});
|
||||
Object.defineProperty(preview, "width", {
|
||||
configurable: true,
|
||||
get: () => undefined,
|
||||
set: () => {},
|
||||
});
|
||||
node.addCustomWidget(preview);
|
||||
|
||||
// Live refresh when widgets change.
|
||||
for (const w of [gapWidget, bgWidget]) {
|
||||
if (w) {
|
||||
const prev = w.callback;
|
||||
w.callback = function () {
|
||||
const r = prev?.apply(this, arguments);
|
||||
refreshThumbs();
|
||||
node.setDirtyCanvas?.(true, true);
|
||||
return r;
|
||||
};
|
||||
}
|
||||
}
|
||||
|
||||
// Watch KJ Get nodes: when their value changes, refresh thumbnails.
|
||||
for (const i of connectedSlots()) {
|
||||
const input = node.inputs?.find((inp) => inp.name === `image${i}`);
|
||||
if (!input || input.link == null) continue;
|
||||
const link = app.graph.links[input.link];
|
||||
if (!link) continue;
|
||||
const src = app.graph._nodes_by_id?.[link.origin_id];
|
||||
if (!src) continue;
|
||||
const srcType = src.type || "";
|
||||
if (!srcType.includes("KJ")) continue;
|
||||
for (const w of src.widgets || []) {
|
||||
const prev = w.callback;
|
||||
w.callback = function () {
|
||||
const r = prev?.apply(this, arguments);
|
||||
refreshThumbs();
|
||||
node.setDirtyCanvas?.(true, true);
|
||||
return r;
|
||||
};
|
||||
}
|
||||
}
|
||||
|
||||
// Watch upstream nodes: crop/path/rotation edits refresh instantly.
|
||||
// The Composer's own onDrawBackground runs on every canvas redraw,
|
||||
// so polling there is cheap (string compares) and always fires —
|
||||
// unlike hooks on the upstream node, which newer ComfyUI versions
|
||||
// may simply never call.
|
||||
const prevBg = node.onDrawBackground;
|
||||
node.onDrawBackground = function () {
|
||||
const r = prevBg?.apply(this, arguments);
|
||||
let changed = false;
|
||||
// Safety net: clean up thumbnail entries for any
|
||||
// inputs that are no longer connected (e.g. bypassed).
|
||||
for (const [key, entry] of state.thumbs) {
|
||||
const i = Number(key);
|
||||
const input = node.inputs?.find((inp) => inp.name === `image${i}`);
|
||||
if (!input || input.link == null) {
|
||||
state.thumbs.delete(key);
|
||||
changed = true;
|
||||
}
|
||||
}
|
||||
for (const i of connectedSlots()) {
|
||||
const cur = upstreamPath(i);
|
||||
const entry = state.thumbs.get(i);
|
||||
if (!cur) {
|
||||
// Upstream invalid (bypassed, broken trace): clear
|
||||
// the thumbnail but keep the entry so a reconnect
|
||||
// can reload it. Only clear if we had a real image
|
||||
// — avoids wiping during transient null returns.
|
||||
if (entry && entry.path && entry.img) {
|
||||
entry.path = "";
|
||||
entry.img = null;
|
||||
changed = true;
|
||||
}
|
||||
continue;
|
||||
}
|
||||
// Upstream cleared (empty path): only clear the thumbnail
|
||||
// when we previously had a real path — avoids wiping
|
||||
// during transient states where upstreamPath returns ""
|
||||
// momentarily (graph rebuilds, node moves, etc.).
|
||||
if (!cur.path) {
|
||||
if (entry && entry.path) {
|
||||
entry.path = "";
|
||||
entry.img = null;
|
||||
changed = true;
|
||||
}
|
||||
continue;
|
||||
}
|
||||
const cropKey = `${cur.crop ? JSON.stringify(cur.crop) : ""}` +
|
||||
`|${cur.maxMp}`;
|
||||
if (entry && (entry.path !== cur.path ||
|
||||
entry.rotation !== cur.rotation ||
|
||||
entry.cropKey !== cropKey)) {
|
||||
entry.path = cur.path;
|
||||
entry.rotation = cur.rotation;
|
||||
entry.crop = cur.crop;
|
||||
entry.maxMp = cur.maxMp;
|
||||
entry.cropKey = cropKey;
|
||||
loadThumb(i, entry);
|
||||
changed = true;
|
||||
} else if (!entry) {
|
||||
const ne = { path: cur.path, rotation: cur.rotation,
|
||||
crop: cur.crop, maxMp: cur.maxMp, cropKey, img: null };
|
||||
state.thumbs.set(i, ne);
|
||||
loadThumb(i, ne);
|
||||
changed = true;
|
||||
}
|
||||
}
|
||||
if (changed) node.setDirtyCanvas?.(true, true);
|
||||
return r;
|
||||
};
|
||||
|
||||
setTimeout(() => {
|
||||
syncInputs();
|
||||
refreshThumbs();
|
||||
// Set up KJ node callbacks now that inputs are synced.
|
||||
for (const i of connectedSlots()) {
|
||||
const input = node.inputs?.find((inp) => inp.name === `image${i}`);
|
||||
if (!input || input.link == null) continue;
|
||||
const link = app.graph.links[input.link];
|
||||
if (!link) continue;
|
||||
const src = app.graph._nodes_by_id?.[link.origin_id];
|
||||
if (!src) continue;
|
||||
const srcType = src.type || "";
|
||||
if (!srcType.includes("KJ")) continue;
|
||||
for (const w of src.widgets || []) {
|
||||
if (w.callback) continue; // already set up
|
||||
const prev = w.callback;
|
||||
w.callback = function () {
|
||||
const r = prev?.apply(this, arguments);
|
||||
refreshThumbs();
|
||||
node.setDirtyCanvas?.(true, true);
|
||||
return r;
|
||||
};
|
||||
}
|
||||
}
|
||||
}, 0);
|
||||
|
||||
const prevOnConfigure = node.onConfigure;
|
||||
node.onConfigure = function () {
|
||||
const r = prevOnConfigure?.apply(this, arguments);
|
||||
setTimeout(() => { syncInputs(); refreshThumbs(); }, 0);
|
||||
return r;
|
||||
};
|
||||
|
||||
return result;
|
||||
};
|
||||
},
|
||||
});
|
||||
|
||||
app.registerExtension({
|
||||
name: "noEmbryo.LoadImageFromPath",
|
||||
|
||||
Reference in New Issue
Block a user