diff --git a/.gitignore b/.gitignore
index 939a120..f4dd76b 100644
--- a/.gitignore
+++ b/.gitignore
@@ -1,2 +1,14 @@
+# Python and IDE
__pycache__/
.vscode/settings.json
+
+# Binary management
+binaries/*
+binaries/win64/*
+binaries/linux/*
+
+# Keep directory structure and rename file for Linux
+!binaries/
+!binaries/win64/
+!binaries/linux/
+!binaries/linux/rename_this_to_keep_user_binary.txt
\ No newline at end of file
diff --git a/README.md b/README.md
index bc72e1c..7c75890 100644
--- a/README.md
+++ b/README.md
@@ -1,5 +1,12 @@
# ComfyUI-MultiGPU
+
+ 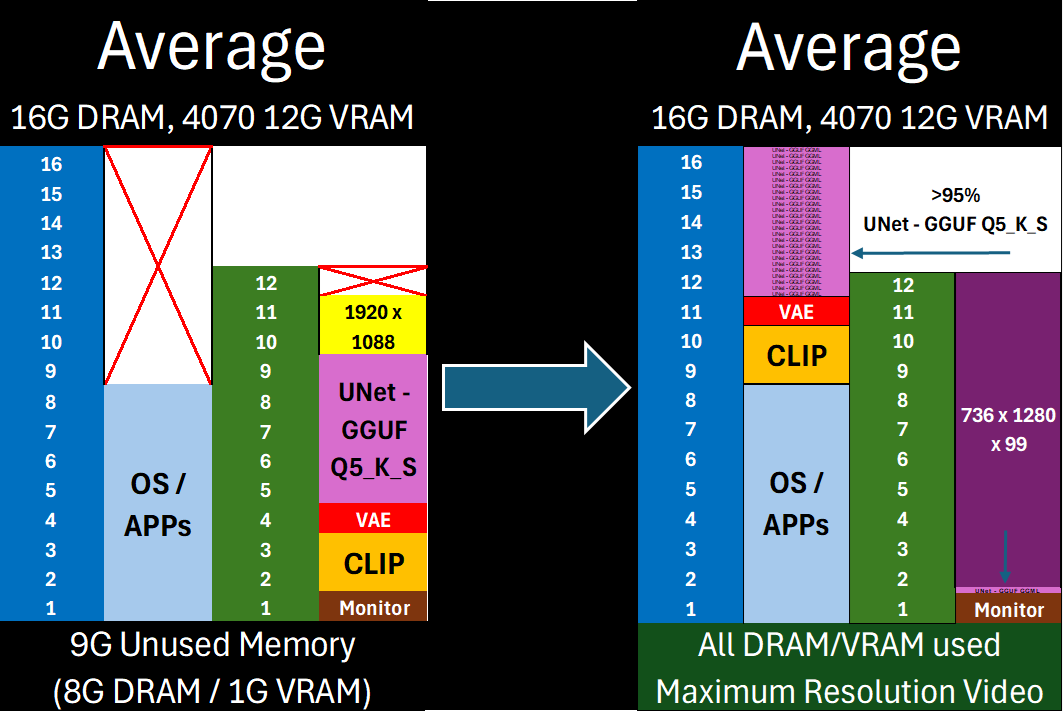 +
+ Add Virtual VRAM and unleash the power of all of your latent space
+
+
+
## Device selection and model offloading tools for ComfyUI workloads that exceed single GPU capacity
This extension empowers users to spread model components across multiple GPUs or offload to CPU in a single ComfyUI workflow. Aimed at complex workloads that would normally require sequential model loading/unloading:
@@ -12,15 +19,61 @@ This extension empowers users to spread model components across multiple GPUs or
**Note:** This enhances memory management, not parallelism. Workflow steps execute sequentially but with components, or in the case of GGUF files `GGML` layers, loaded across your specified devices. *Performance gains* come from avoiding repeated model loading/unloading when VRAM is constrained. *Capability gains* come from offloading as much of the model (VAE/CLIP/UNet) off of your main `compute` device, allowing you to maximize the amount of latent space available for `compute`
-# NEW: DisTorch - Advanced GGUF-Quantized Model Layer Distribution
+**NEW** DisTorch 2.0: Virtual VRAM Made Simple
-DisTorch nodes are now available, allowing fine-grained control over model layer distribution across multiple devices for GGUF quantized models. Using a simple allocation string (e.g., "cuda:0,0.025;cuda:1,0.05;cpu,0.10"), you can precisely specify how much memory each device should contribute to hosting model layers. This enables sophisticated memory management strategies like:
+
+ 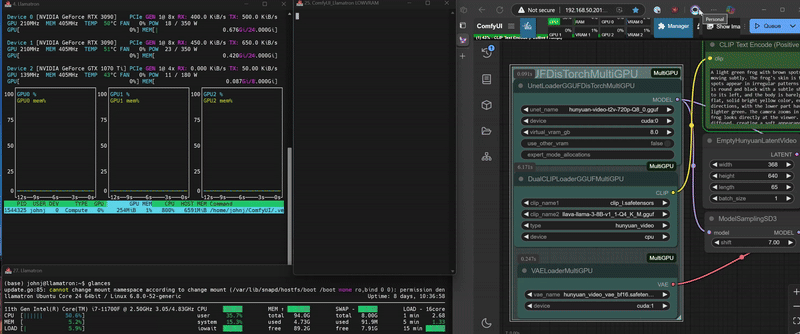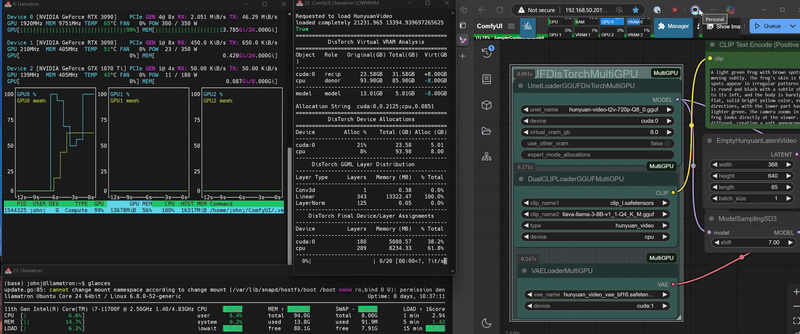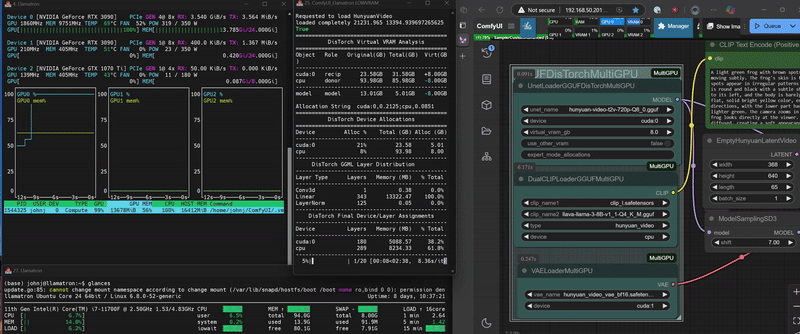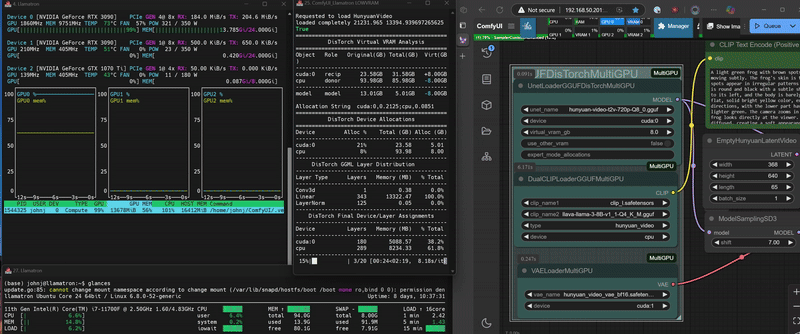 +
+ DisTorch 2.0 in Action
+
-- Splitting large models across multiple GPUs with different VRAM capacities
-- Utilizing CPU memory alongside GPU VRAM for handling memory-intensive models
-- Optimizing layer placement based on your specific hardware configuration
-Check out the updated examples `hunyuan_ip2v_distorch_gguf.json`, `hunyuan_gguf_distorch.json`, and `flux1dev_gguf_distorch.json` to see DisTorch in action, demonstrating advanced layer distribution across multiple devices including adapting kijai's `HunyuanVideo TextImageEncode (IP2V)` node for the native HunyuanVideo sampler in Comfy Core - meaning HunyuanVideo with IP2V has come to GGUFs!
+
+## What's New?
+DisTorch now features simple Virtual VRAM control that lets you offload model layers from your GPU with zero configuration. Just set how much VRAM you want to free up, and DisTorch handles the rest.
+
+## How It Works
+- **Virtual VRAM**: Defaults to 4GB - just adjust it based on your needs
+- **Two Modes**:
+ - **Default**: Offloads to system RAM
+ - **Multi-GPU**: Distributes across other GPUs (optional)
+
+## 🎯 Key Benefits
+- Free up GPU VRAM instantly without complex settings
+- Run larger models by offloading layers to other system RAM
+- Use all your main GPU's VRAM for actual `compute` / latent processing
+- Seamlessly distribute GGML layers across multiple GPUs if available
+- Allows **you** to easily shift from ___on-device speed___ to ___open-device capability___ with a simple one-number change
+
+
+ 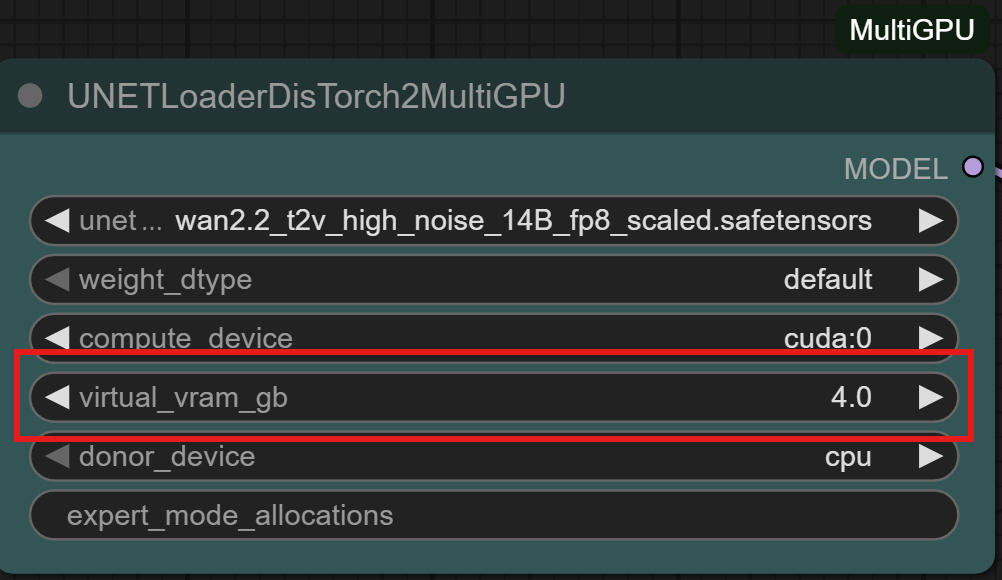 +
+ DisTorch 2.0 Node with one simple number to tune its Vitual VRAM to your needs
+
+
+## 💡 Quick Start
+1. Load any GGUF model using a DisTorch node
+2. Set your Virtual VRAM amount (default: 4GB, in this example we chose 8GB)
+3. Toggle "Use Other VRAM" if you have multiple GPUs[^1]
+4. That's it!
+[^1]: DisTorch's Virtual VRAM aims to span as few a devices as possible. I recommend users try both ways (VRAM/DRAM) and see which works best for you.
+
+## 🔄 Real-World Example
+With a 12GB GPU running an 8GB model:
+- Set Virtual VRAM to 4GB
+- DisTorch moves 4GB of model layers to RAM
+- Your GPU now has extra VRAM for larger batches, higher resolutions, or longer video
+
+## 🚀 Compatibility
+Works with all GGUF-quantized ComfyUI/ComfyUI-GGUF-supported UNet/CLIP models.
+
+⚙️ Expert users: For those of you who were here for the 1.0 release of DisTorch, manual allocation strings still available for advanced configurations. Each log will contain the allocation string for the run so it can be easily recreated and/or manipulated for more sophisticated setups.
+
+
+ 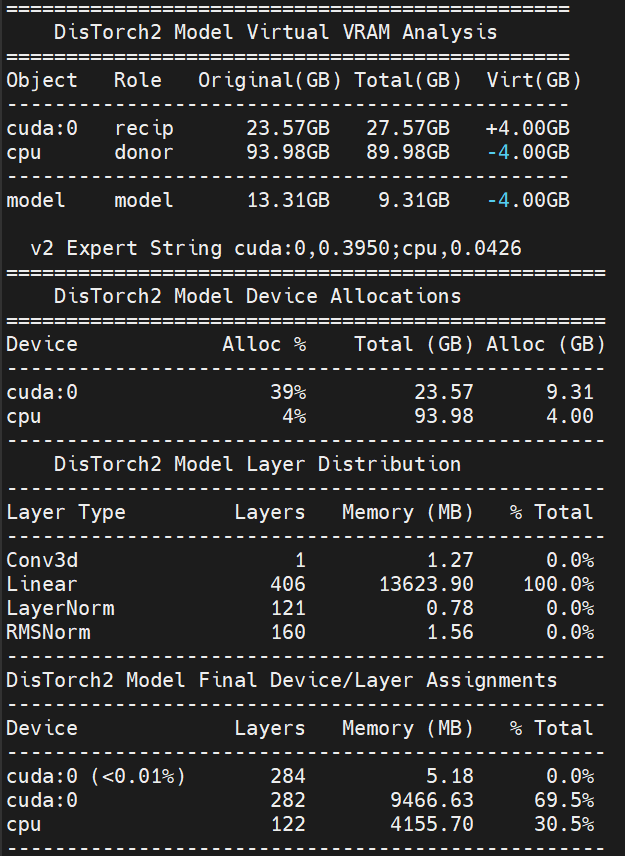 +
+ The new Virtual VRAM even lets you offload ALL of the model and still run compute on your CUDA device!
+
## Installation
@@ -85,11 +138,6 @@ This workflow attaches a HunyuanVideo GGUF-quantized model on `cuda:0` for compu
- [examples/flux1dev_gguf_distorch.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/flux1dev_gguf_distorch.json)
This workflow loads a FLUX.1-dev model on `cuda:0` for compute and distrubutes its UNet across multiple CUDA devices using new DisTorch distributed-load methodology. While the text encoders and VAE are loaded on GPU 1 and use `cuda:1` for compute.
-### Split Hunyuan Video UNet across two devices and use DiffSynth Just-in-Time loading
-
-- [examples/hunyuanvideowrapper_diffsynth.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/hunyuanvideowrapper_diffsynth.json)
-This workflow demonstrates DiffSynth's memory optimization strategy enabled in kijai's `ComfyUI-HunyuanVideoWrapper` UNet loader, splitting the UNet model across two CUDA devices using block-swapping. The main device handles active computations while blocks are swapped to and from the offload device as needed. As written, the CLIP loads on cuda:0 and then offloads, and the VAE is loaded after the UNet model has been cleared from memory after generation. This approach enables processing of higher resolution or longer duration videos that would exceed a single GPU's memory capacity, though at the cost of additional processing time. Note that an initial OOM error is expected as the workflow calibrates its memory management strategy - simply run the generation again with the same parameters.
-
### Split Hunyuan Video generation across multiple resources
- [examples/hunyuanvideowrapper_native_vae.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/hunyuanvideowrapper_native_vae.json)
diff --git a/__init__.py b/__init__.py
index 0d574d6..ae0003c 100644
--- a/__init__.py
+++ b/__init__.py
@@ -1,4 +1,3 @@
-# __init__.py
import copy
import torch
import sys
@@ -7,8 +6,29 @@ import os
from pathlib import Path
import logging
import folder_paths
+import shutil
from collections import defaultdict
import hashlib
+import tempfile
+import subprocess
+import gc
+from safetensors.torch import save_file, load_file
+import comfy.utils
+from typing import Dict, List
+
+
+from nodes import NODE_CLASS_MAPPINGS as GLOBAL_NODE_CLASS_MAPPINGS
+from .nodes import (
+ UnetLoaderGGUF, UnetLoaderGGUFAdvanced,
+ CLIPLoaderGGUF, DualCLIPLoaderGGUF, TripleCLIPLoaderGGUF,
+ LTXVLoader,
+ Florence2ModelLoader, DownloadAndLoadFlorence2Model,
+ CheckpointLoaderNF4,
+ LoadFluxControlNet,
+ MMAudioModelLoader, MMAudioFeatureUtilsLoader, MMAudioSampler,
+ PulidModelLoader, PulidInsightFaceLoader, PulidEvaClipLoader,
+ HyVideoModelLoader, HyVideoVAELoader, DownloadAndLoadHyVideoTextEncoder
+)
current_device = mm.get_torch_device()
model_allocation_store = {}
@@ -79,8 +99,19 @@ def register_patched_ggufmodelpatcher():
def analyze_ggml_loading(model, allocations_str):
DEVICE_RATIOS_DISTORCH = {}
device_table = {}
+ distorch_alloc = allocations_str
+ virtual_vram_gb = 0.0
- for allocation in allocations_str.split(';'):
+ if '#' in allocations_str:
+ distorch_alloc, virtual_vram_str = allocations_str.split('#')
+ if not distorch_alloc:
+ distorch_alloc = calculate_vvram_allocation_string(model, virtual_vram_str)
+
+ eq_line = "=" * 47
+ dash_line = "-" * 47
+ fmt_assign = "{:<12}{:>10}{:>14}{:>10}"
+
+ for allocation in distorch_alloc.split(';'):
dev_name, fraction = allocation.split(',')
fraction = float(fraction)
total_mem_bytes = mm.get_total_memory(torch.device(dev_name))
@@ -92,17 +123,11 @@ def analyze_ggml_loading(model, allocations_str):
"alloc_gb": alloc_gb
}
- eq_line = "=" * 47
- dash_line = "-" * 47
- fmt_alloc = "{:<12}{:>10}{:>14}{:>10}"
logging.basicConfig(level=logging.INFO, format='%(asctime)s - %(levelname)s - %(message)s')
logging.info(eq_line)
- logging.info(" DisTorch Analysis")
- logging.info(eq_line)
- logging.info(dash_line)
logging.info(" DisTorch Device Allocations")
- logging.info(dash_line)
- logging.info(fmt_alloc.format("Device", "Alloc %", "Total (GB)", " Alloc (GB)"))
+ logging.info(eq_line)
+ logging.info(fmt_assign.format("Device", "Alloc %", "Total (GB)", " Alloc (GB)"))
logging.info(dash_line)
sorted_devices = sorted(device_table.keys(), key=lambda d: (d == "cpu", d))
@@ -111,7 +136,7 @@ def analyze_ggml_loading(model, allocations_str):
frac = device_table[dev]["fraction"]
tot_gb = device_table[dev]["total_gb"]
alloc_gb = device_table[dev]["alloc_gb"]
- logging.info(fmt_alloc.format(dev,f"{int(frac * 100)}%",f"{tot_gb:.2f}",f"{alloc_gb:.2f}"))
+ logging.info(fmt_assign.format(dev,f"{int(frac * 100)}%",f"{tot_gb:.2f}",f"{alloc_gb:.2f}"))
logging.info(dash_line)
@@ -189,6 +214,102 @@ def analyze_ggml_loading(model, allocations_str):
return {"device_assignments": device_assignments}
+def calculate_vvram_allocation_string(model, virtual_vram_str):
+ recipient_device, vram_amount, donors = virtual_vram_str.split(';')
+ virtual_vram_gb = float(vram_amount)
+
+ eq_line = "=" * 47
+ dash_line = "-" * 47
+ fmt_assign = "{:<8} {:<6} {:>11} {:>9} {:>9}"
+
+ logging.basicConfig(level=logging.INFO, format='%(asctime)s - %(levelname)s - %(message)s')
+ logging.info(eq_line)
+ logging.info(" DisTorch Virtual VRAM Analysis")
+ logging.info(eq_line)
+ logging.info(fmt_assign.format("Object", "Role", "Original(GB)", "Total(GB)", "Virt(GB)"))
+ logging.info(dash_line)
+
+ recipient_vram = mm.get_total_memory(torch.device(recipient_device)) / (1024**3)
+ recipient_virtual = recipient_vram + virtual_vram_gb
+
+ logging.info(fmt_assign.format(recipient_device, 'recip', f"{recipient_vram:.2f}GB",f"{recipient_virtual:.2f}GB", f"+{virtual_vram_gb:.2f}GB"))
+
+ ram_donors = [d for d in donors.split(',') if d != 'cpu']
+ remaining_vram_needed = virtual_vram_gb
+
+ donor_device_info = {}
+ donor_allocations = {}
+
+ for donor in ram_donors:
+ donor_vram = mm.get_total_memory(torch.device(donor)) / (1024**3)
+ max_donor_capacity = donor_vram * 0.9
+
+ donation = min(remaining_vram_needed, max_donor_capacity)
+ donor_virtual = donor_vram - donation
+ remaining_vram_needed -= donation
+ donor_allocations[donor] = donation
+
+ donor_device_info[donor] = (donor_vram, donor_virtual)
+ logging.info(fmt_assign.format(donor, 'donor', f"{donor_vram:.2f}GB", f"{donor_virtual:.2f}GB", f"-{donation:.2f}GB"))
+
+ system_dram_gb = mm.get_total_memory(torch.device('cpu')) / (1024**3)
+ cpu_donation = remaining_vram_needed
+ cpu_virtual = system_dram_gb - cpu_donation
+ donor_allocations['cpu'] = cpu_donation
+ logging.info(fmt_assign.format('cpu', 'donor', f"{system_dram_gb:.2f}GB", f"{cpu_virtual:.2f}GB", f"-{cpu_donation:.2f}GB"))
+
+ logging.info(dash_line)
+
+ layer_summary = {}
+ layer_list = []
+ memory_by_type = defaultdict(int)
+ total_memory = 0
+
+ for name, module in model.named_modules():
+ if hasattr(module, "weight"):
+ layer_type = type(module).__name__
+ layer_summary[layer_type] = layer_summary.get(layer_type, 0) + 1
+ layer_list.append((name, module, layer_type))
+ layer_memory = 0
+ if module.weight is not None:
+ layer_memory += module.weight.numel() * module.weight.element_size()
+ if hasattr(module, "bias") and module.bias is not None:
+ layer_memory += module.bias.numel() * module.bias.element_size()
+ memory_by_type[layer_type] += layer_memory
+ total_memory += layer_memory
+
+ model_size_gb = total_memory / (1024**3)
+ new_model_size_gb = max(0, model_size_gb - virtual_vram_gb)
+
+ logging.info(fmt_assign.format('model', 'model', f"{model_size_gb:.2f}GB",f"{new_model_size_gb:.2f}GB", f"-{virtual_vram_gb:.2f}GB"))
+
+ if model_size_gb > (recipient_vram * 0.9):
+ on_recipient = recipient_vram * 0.9
+ on_virtuals = model_size_gb - on_recipient
+ logging.info(f"\nWarning: Model size is greater than 90% of recipient VRAM. {on_virtuals:.2f} GB of GGML Layers Offloaded Automatically to Virtual VRAM.\n")
+ else:
+ on_recipient = model_size_gb
+ on_virtuals = 0
+
+ new_on_recipient = max(0, on_recipient - virtual_vram_gb)
+
+ allocation_parts = []
+ recipient_percent = new_on_recipient / recipient_vram
+ allocation_parts.append(f"{recipient_device},{recipient_percent:.4f}")
+
+ for donor in ram_donors:
+ donor_vram = donor_device_info[donor][0]
+ donor_percent = donor_allocations[donor] / donor_vram
+ allocation_parts.append(f"{donor},{donor_percent:.4f}")
+
+ cpu_percent = donor_allocations['cpu'] / system_dram_gb
+ allocation_parts.append(f"cpu,{cpu_percent:.4f}")
+
+ allocation_string = ";".join(allocation_parts)
+ fmt_mem = "{:<20}{:>20}"
+ logging.info(fmt_mem.format("\nAllocation String", allocation_string))
+
+ return allocation_string
def get_device_list():
import torch
@@ -226,29 +347,159 @@ class HunyuanVideoEmbeddingsAdapter:
CATEGORY = "multigpu"
def adapt_embeddings(self, hyvid_embeds):
- # Create main conditioning tensor
cond = hyvid_embeds["prompt_embeds"]
- # Create pooled dict with all our extra information
pooled_dict = {
"pooled_output": hyvid_embeds["prompt_embeds_2"],
"cross_attn": hyvid_embeds["prompt_embeds"],
"attention_mask": hyvid_embeds["attention_mask"],
}
- # Add CLIP's attention mask if present
if hyvid_embeds["attention_mask_2"] is not None:
pooled_dict["attention_mask_controlnet"] = hyvid_embeds["attention_mask_2"]
- # Add guidance if present - typically these and negative_xxxx are empty for HunyuanVideo
if hyvid_embeds["cfg"] is not None:
pooled_dict["guidance"] = float(hyvid_embeds["cfg"])
pooled_dict["start_percent"] = float(hyvid_embeds["start_percent"]) if hyvid_embeds["start_percent"] is not None else 0.0
pooled_dict["end_percent"] = float(hyvid_embeds["end_percent"]) if hyvid_embeds["end_percent"] is not None else 1.0
- # Finally create the conditioning list in the exact format that encode_from_tokens_scheduled returns
return ([[cond, pooled_dict]],)
+
+class MergeFluxLoRAsQuantizeAndLoad:
+ @classmethod
+ def INPUT_TYPES(cls):
+ unet_name = folder_paths.get_filename_list("diffusion_models")
+ loras = ["None"] + folder_paths.get_filename_list("loras")
+ inputs = {
+ "required": {
+ "unet_name": (unet_name,),
+ "switch_1": (["Off", "On"],),
+ "lora_name_1": (loras,),
+ "lora_weight_1": ("FLOAT", {"default": 1.0, "min": -10.0, "max": 10.0, "step": 0.01}),
+ "switch_2": (["Off", "On"],),
+ "lora_name_2": (loras,),
+ "lora_weight_2": ("FLOAT", {"default": 1.0, "min": -10.0, "max": 10.0, "step": 0.01}),
+ "switch_3": (["Off", "On"],),
+ "lora_name_3": (loras,),
+ "lora_weight_3": ("FLOAT", {"default": 1.0, "min": -10.0, "max": 10.0, "step": 0.01}),
+ "switch_4": (["Off", "On"],),
+ "lora_name_4": (loras,),
+ "lora_weight_4": ("FLOAT", {"default": 1.0, "min": -10.0, "max": 10.0, "step": 0.01}),
+ "quantization": (["Q2_K", "Q3_K_S", "Q4_0", "Q4_1", "Q4_K_S", "Q5_0", "Q5_1", "Q5_K_S", "Q6_K", "Q8_0", "FP16"], {"default": "Q4_K_S"}),
+ "delete_final_gguf": ("BOOLEAN", {"default": False}),
+ "new_model_name": ("STRING", {"default": "merged_model"}),
+ }
+ }
+ return inputs
+
+ RETURN_TYPES = ("MODEL",)
+ FUNCTION = "load_and_quantize"
+ CATEGORY = "loaders"
+
+ def merge_flux_loras(self, model_sd: dict, lora_paths: list, weights: list, device="cuda") -> dict:
+ for lora_path, weight in zip(lora_paths, weights):
+ logging.info(f"[DEBUG] Merging LoRA file: {lora_path} with weight: {weight}")
+ lora_sd = load_file(lora_path, device=device)
+ for key in list(lora_sd.keys()):
+ if "lora_down" not in key:
+ continue
+ base_name = key[: key.rfind(".lora_down")]
+ up_key = key.replace("lora_down", "lora_up")
+ module_name = base_name.replace("_", ".")
+ alpha_key = f"{base_name}.alpha"
+ if module_name not in model_sd:
+ logging.info(f"[DEBUG] Module {module_name} not found in model_sd; skipping key {key}")
+ continue
+ down_weight = lora_sd[key].float()
+ up_weight = lora_sd[up_key].float()
+ alpha = float(lora_sd.get(alpha_key, up_weight.shape[0]))
+ scale = weight * alpha / up_weight.shape[0]
+ logging.info(f"[DEBUG] Merging module: {module_name} with alpha: {alpha}, scale: {scale}")
+ target_weight = model_sd[module_name]
+ if len(target_weight.shape) == 2:
+ update = (up_weight @ down_weight) * scale
+ else:
+ if down_weight.shape[2:4] == (1, 1):
+ update = (up_weight.squeeze(3).squeeze(2) @ down_weight.squeeze(3).squeeze(2))
+ update = update.unsqueeze(2).unsqueeze(3) * scale
+ else:
+ update = torch.nn.functional.conv2d(
+ down_weight.permute(1, 0, 2, 3), up_weight
+ ).permute(1, 0, 2, 3) * scale
+ model_sd[module_name] = target_weight + update.to(target_weight.dtype)
+ logging.info(f"[DEBUG] Updated module: {module_name}")
+ del up_weight, down_weight, update
+ del lora_sd
+ torch.cuda.empty_cache()
+ return model_sd
+
+ def convert_to_gguf(self, model_path, working_dir):
+ base_path = os.path.dirname(os.path.dirname(os.path.abspath(__file__)))
+ convert_script = os.path.join(base_path, "ComfyUI-GGUF", "tools", "convert.py")
+ temp_gguf = os.path.join(working_dir, "temp_converted.gguf")
+ logging.info("[DEBUG] Running conversion script: " + convert_script)
+ subprocess.run([sys.executable, convert_script, "--src", model_path, "--dst", temp_gguf], check=True)
+ logging.info("[DEBUG] Conversion complete.")
+ return temp_gguf
+
+ def load_and_quantize(self, unet_name, quantization, delete_final_gguf, new_model_name, **kwargs):
+ mapping = {"FP16": "F16"}
+ logging.info(f"[DEBUG] Starting load_and_quantize: {new_model_name} | Quantization: {quantization}")
+ with tempfile.TemporaryDirectory() as merge_dir:
+ merged_model_path = os.path.join(merge_dir, "merged_model.safetensors")
+ model_path = folder_paths.get_full_path("diffusion_models", unet_name)
+ lora_list = []
+ for i in range(1, 5):
+ name = kwargs.get(f"lora_name_{i}", "None")
+ switch = kwargs.get(f"switch_{i}", "Off")
+ logging.info(f"[DEBUG] Processing LoRA slot {i}: name = {name}, switch = {switch}")
+ if switch == "On" and name and name != "None":
+ lora_file_path = folder_paths.get_full_path("loras", name)
+ weight = kwargs.get(f"lora_weight_{i}", 1.0)
+ lora_list.append((lora_file_path, weight))
+ logging.info(f"[DEBUG] Slot {i} active: path = {lora_file_path}, weight = {weight}")
+ else:
+ logging.info(f"[DEBUG] Slot {i} is inactive")
+ logging.info(f"[DEBUG] Total active LoRAs: {len(lora_list)}")
+ if lora_list:
+ model_sd = load_file(model_path, device="cuda")
+ model_sd = self.merge_flux_loras(
+ model_sd,
+ [lp for lp, _ in lora_list],
+ [w for _, w in lora_list]
+ )
+ save_file(model_sd, merged_model_path)
+ del model_sd
+ torch.cuda.empty_cache()
+ else:
+ shutil.copy2(model_path, merged_model_path)
+ initial_gguf = self.convert_to_gguf(merged_model_path, merge_dir)
+ logging.info("[DEBUG] Initial GGUF file created.")
+ if quantization == "FP16":
+ final_gguf = os.path.join(merge_dir, f"{new_model_name}-{mapping.get(quantization, quantization)}.gguf")
+ shutil.copy2(initial_gguf, final_gguf)
+ logging.info("[DEBUG] FP16 selected; conversion skipped.")
+ else:
+ binary = os.path.join(os.path.dirname(os.path.abspath(__file__)), "binaries", "linux", "llama-quantize")
+ final_gguf = os.path.join(merge_dir, f"quantized_{quantization}.gguf")
+ subprocess.run([binary, initial_gguf, final_gguf, quantization], check=True)
+ logging.info("[DEBUG] Quantization completed.")
+ models_dir = os.path.join(folder_paths.models_dir, "unet")
+ os.makedirs(models_dir, exist_ok=True)
+ final_name = f"{new_model_name}-{mapping.get(quantization, quantization)}.gguf"
+ final_path = os.path.join(models_dir, final_name)
+ shutil.copy2(final_gguf, final_path)
+ logging.info("[DEBUG] Final model file copied to: " + final_path)
+ logging.info("[DEBUG] Loading final model.")
+ loader = UnetLoaderGGUF()
+ result = loader.load_unet(final_name)
+ logging.info("[DEBUG] Final model loaded.")
+ if delete_final_gguf:
+ os.unlink(final_path)
+ return result
+
+
def override_class(cls):
class NodeOverride(cls):
@classmethod
@@ -282,677 +533,115 @@ def override_class_with_distorch(cls):
default_device = devices[1] if len(devices) > 1 else devices[0]
inputs["optional"] = inputs.get("optional", {})
inputs["optional"]["device"] = (devices, {"default": default_device})
- inputs["optional"]["allocations"] = ("STRING", {"multiline": False, "default": "cuda:0,0.15;cpu,0.5"})
+ inputs["optional"]["virtual_vram_gb"] = ("FLOAT", {"default": 4.0, "min": 0.0, "max": 24.0, "step": 0.1})
+ inputs["optional"]["use_other_vram"] = ("BOOLEAN", {"default": False})
+ inputs["optional"]["expert_mode_allocations"] = ("STRING", {
+ "multiline": False,
+ "default": "",
+ "tooltip": "Expert use only: Manual VRAM allocation string. Incorrect values can cause crashes. Do not modify unless you fully understand DisTorch memory management."
+ })
return inputs
CATEGORY = "multigpu"
FUNCTION = "override"
- def override(self, *args, device=None, allocations=None, **kwargs):
+ def override(self, *args, device=None, expert_mode_allocations=None, use_other_vram=None, virtual_vram_gb=0.0, **kwargs):
global current_device
if device is not None:
current_device = device
-
+
register_patched_ggufmodelpatcher()
fn = getattr(super(), cls.FUNCTION)
out = fn(*args, **kwargs)
+ vram_string = ""
+ if virtual_vram_gb > 0:
+ if use_other_vram:
+ available_devices = [d for d in get_device_list() if d.startswith('cuda')]
+ other_devices = [d for d in available_devices if d != device]
+ other_devices.sort(key=lambda x: int(x.split(':')[1] if ':' in x else x[-1]), reverse=False)
+ device_string = ','.join(other_devices + ['cpu'])
+ vram_string = f"{device};{virtual_vram_gb};{device_string}"
+ else:
+ vram_string = f"{device};{virtual_vram_gb};cpu"
+
+ full_allocation = f"{expert_mode_allocations}#{vram_string}" if expert_mode_allocations or vram_string else ""
+
+ logging.info(f"[DisTorch] Full allocation string: {full_allocation}")
+
if hasattr(out[0], 'model'):
model_hash = create_model_hash(out[0], "override")
- model_allocation_store[model_hash] = allocations
+ model_allocation_store[model_hash] = full_allocation
elif hasattr(out[0], 'patcher') and hasattr(out[0].patcher, 'model'):
model_hash = create_model_hash(out[0].patcher, "override")
- model_allocation_store[model_hash] = allocations
+ model_allocation_store[model_hash] = full_allocation
return out
return NodeOverrideDisTorch
+def check_module_exists(module_path):
+ full_path = os.path.join(folder_paths.get_folder_paths("custom_nodes")[0], module_path)
+ logging.info(f"MultiGPU: Checking for module at {full_path}")
+ if not os.path.exists(full_path):
+ logging.info(f"MultiGPU: Module {module_path} not found - skipping")
+ return False
+ logging.info(f"MultiGPU: Found {module_path}, creating compatible MultiGPU nodes")
+ return True
NODE_CLASS_MAPPINGS = {
"DeviceSelectorMultiGPU": DeviceSelectorMultiGPU,
"HunyuanVideoEmbeddingsAdapter": HunyuanVideoEmbeddingsAdapter,
}
-def check_module_exists(module_path):
- full_path = os.path.join(folder_paths.get_folder_paths("custom_nodes")[0], module_path)
- logging.info(f"MultiGPU: Checking for module at {full_path}")
+NODE_CLASS_MAPPINGS["MergeFluxLoRAsQuantizeAndLoaddMultiGPU"] = override_class(MergeFluxLoRAsQuantizeAndLoad)
- if not os.path.exists(full_path):
- logging.info(f"MultiGPU: Module {module_path} not found - skipping")
- return False
+NODE_CLASS_MAPPINGS["UNETLoaderMultiGPU"] = override_class(GLOBAL_NODE_CLASS_MAPPINGS["UNETLoader"])
+NODE_CLASS_MAPPINGS["VAELoaderMultiGPU"] = override_class(GLOBAL_NODE_CLASS_MAPPINGS["VAELoader"])
+NODE_CLASS_MAPPINGS["CLIPLoaderMultiGPU"] = override_class(GLOBAL_NODE_CLASS_MAPPINGS["CLIPLoader"])
+NODE_CLASS_MAPPINGS["DualCLIPLoaderMultiGPU"] = override_class(GLOBAL_NODE_CLASS_MAPPINGS["DualCLIPLoader"])
+NODE_CLASS_MAPPINGS["TripleCLIPLoaderMultiGPU"] = override_class(GLOBAL_NODE_CLASS_MAPPINGS["TripleCLIPLoader"])
+NODE_CLASS_MAPPINGS["CheckpointLoaderSimpleMultiGPU"] = override_class(GLOBAL_NODE_CLASS_MAPPINGS["CheckpointLoaderSimple"])
+NODE_CLASS_MAPPINGS["ControlNetLoaderMultiGPU"] = override_class(GLOBAL_NODE_CLASS_MAPPINGS["ControlNetLoader"])
- logging.info(f"MultiGPU: Found {module_path}, creating compatible MultiGPU nodes")
- return True
-
-def register_module(target_nodes):
- from nodes import NODE_CLASS_MAPPINGS as GLOBAL_NODE_CLASS_MAPPINGS
-
- for node in target_nodes:
- NODE_CLASS_MAPPINGS[f"{node}MultiGPU"] = override_class(GLOBAL_NODE_CLASS_MAPPINGS[node])
- return
-
-def register_UnetLoaderGGUFMultiGPU():
- global NODE_CLASS_MAPPINGS
-
- class UnetLoaderGGUF:
- @classmethod
- def INPUT_TYPES(s):
- unet_names = [x for x in folder_paths.get_filename_list("unet_gguf")]
- return {
- "required": {
- "unet_name": (unet_names,),
- }
- }
-
- RETURN_TYPES = ("MODEL",)
- FUNCTION = "load_unet"
- CATEGORY = "bootleg"
- TITLE = "Unet Loader (GGUF)"
-
- def load_unet(self, unet_name, dequant_dtype=None, patch_dtype=None, patch_on_device=None):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["UnetLoaderGGUF"]()
- return original_loader.load_unet(unet_name, dequant_dtype, patch_dtype, patch_on_device)
-
- # Create both MultiGPU versions of the base class
- UnetLoaderGGUFMultiGPU = override_class(UnetLoaderGGUF)
- NODE_CLASS_MAPPINGS["UnetLoaderGGUFMultiGPU"] = UnetLoaderGGUFMultiGPU
- logging.info(f"MultiGPU: Registered UnetLoaderGGUFMultiGPU")
-
- UnetLoaderGGUFDisTorchMultiGPU = override_class_with_distorch(UnetLoaderGGUF)
- NODE_CLASS_MAPPINGS["UnetLoaderGGUFDisTorchMultiGPU"] = UnetLoaderGGUFDisTorchMultiGPU
- logging.info(f"MultiGPU: Registered UnetLoaderGGUFDisTorchMultiGPU")
-
- class UnetLoaderGGUFAdvanced(UnetLoaderGGUF):
- @classmethod
- def INPUT_TYPES(s):
- unet_names = [x for x in folder_paths.get_filename_list("unet_gguf")]
- return {
- "required": {
- "unet_name": (unet_names,),
- "dequant_dtype": (["default", "target", "float32", "float16", "bfloat16"], {"default": "default"}),
- "patch_dtype": (["default", "target", "float32", "float16", "bfloat16"], {"default": "default"}),
- "patch_on_device": ("BOOLEAN", {"default": False}),
- }
- }
- TITLE = "Unet Loader (GGUF/Advanced)"
-
- # Create both MultiGPU versions of the advanced class
- UnetLoaderGGUFAdvancedMultiGPU = override_class(UnetLoaderGGUFAdvanced)
- NODE_CLASS_MAPPINGS["UnetLoaderGGUFAdvancedMultiGPU"] = UnetLoaderGGUFAdvancedMultiGPU
- logging.info(f"MultiGPU: Registered UnetLoaderGGUFAdvancedMultiGPU")
-
- UnetLoaderGGUFAdvancedDisTorchMultiGPU = override_class_with_distorch(UnetLoaderGGUFAdvanced)
- NODE_CLASS_MAPPINGS["UnetLoaderGGUFAdvancedDisTorchMultiGPU"] = UnetLoaderGGUFAdvancedDisTorchMultiGPU
- logging.info(f"MultiGPU: Registered UnetLoaderGGUFAdvancedDisTorchMultiGPU")
-
-def register_CLIPLoaderGGUFMultiGPU():
- global NODE_CLASS_MAPPINGS
-
- class CLIPLoaderGGUF:
- @classmethod
- def INPUT_TYPES(s):
- return {
- "required": {
- "clip_name": (s.get_filename_list(),),
- "type": (["stable_diffusion", "stable_cascade", "sd3", "stable_audio", "mochi", "ltxv"],),
- }
- }
-
- RETURN_TYPES = ("CLIP",)
- FUNCTION = "load_clip"
- CATEGORY = "bootleg"
- TITLE = "CLIPLoader (GGUF)"
-
- @classmethod
- def get_filename_list(s):
- files = []
- files += folder_paths.get_filename_list("clip")
- files += folder_paths.get_filename_list("clip_gguf")
- return sorted(files)
-
- def load_data(self, ckpt_paths):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["CLIPLoaderGGUF"]()
- return original_loader.load_data(ckpt_paths)
-
- def load_patcher(self, clip_paths, clip_type, clip_data):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["CLIPLoaderGGUF"]()
- return original_loader.load_patcher(clip_paths, clip_type, clip_data)
-
- def load_clip(self, clip_name, type="stable_diffusion"):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["CLIPLoaderGGUF"]()
- return original_loader.load_clip(clip_name, type)
-
- # Create the MultiGPU version of the base class
- CLIPLoaderGGUFMultiGPU = override_class(CLIPLoaderGGUF)
- NODE_CLASS_MAPPINGS["CLIPLoaderGGUFMultiGPU"] = CLIPLoaderGGUFMultiGPU
- logging.info(f"MultiGPU: Registered CLIPLoaderGGUFMultiGPU")
-
- CLIPLoaderGGUFDisTorchMultiGPU = override_class_with_distorch(CLIPLoaderGGUF)
- NODE_CLASS_MAPPINGS["CLIPLoaderGGUFDisTorchMultiGPU"] = CLIPLoaderGGUFDisTorchMultiGPU
- logging.info(f"MultiGPU: Registered CLIPLoaderGGUFDisTorchMultiGPU")
-
- # Now create the advanced version that inherits from the MultiGPU base class
-
- class DualCLIPLoaderGGUF(CLIPLoaderGGUF):
- @classmethod
- def INPUT_TYPES(s):
- file_options = (s.get_filename_list(), )
- return {
- "required": {
- "clip_name1": file_options,
- "clip_name2": file_options,
- "type": (("sdxl", "sd3", "flux", "hunyuan_video"),),
- }
- }
-
- TITLE = "DualCLIPLoader (GGUF)"
-
- def load_clip(self, clip_name1, clip_name2, type):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["DualCLIPLoaderGGUF"]()
- clip = original_loader.load_clip(clip_name1, clip_name2, type)
- clip[0].patcher.load(force_patch_weights=True)
- return clip
- # Create the MultiGPU version of the advanced class
- DualCLIPLoaderGGUFMultiGPU = override_class(DualCLIPLoaderGGUF)
- NODE_CLASS_MAPPINGS["DualCLIPLoaderGGUFMultiGPU"] = DualCLIPLoaderGGUFMultiGPU
- logging.info(f"MultiGPU: Registered DualCLIPLoaderGGUFMultiGPU")
-
- DualCLIPLoaderGGUFDisTorchMultiGPU = override_class_with_distorch(DualCLIPLoaderGGUF)
- NODE_CLASS_MAPPINGS["DualCLIPLoaderGGUFDisTorchMultiGPU"] = DualCLIPLoaderGGUFDisTorchMultiGPU
- logging.info(f"MultiGPU: Registered DualCLIPLoaderGGUFDisTorchMultiGPU")
-
- class TripleCLIPLoaderGGUF(CLIPLoaderGGUF):
- @classmethod
- def INPUT_TYPES(s):
- file_options = (s.get_filename_list(), )
- return {
- "required": {
- "clip_name1": file_options,
- "clip_name2": file_options,
- "clip_name3": file_options,
- }
- }
-
- TITLE = "TripleCLIPLoader (GGUF)"
-
- def load_clip(self, clip_name1, clip_name2, clip_name3, type="sd3"):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["TripleCLIPLoaderGGUF"]()
- return original_loader.load_clip(clip_name1, clip_name2, clip_name3, type)
- # Create the MultiGPU version of the advanced class
- TripleCLIPLoaderGGUFMultiGPU = override_class(TripleCLIPLoaderGGUF)
- NODE_CLASS_MAPPINGS["TripleCLIPLoaderGGUFMultiGPU"] = TripleCLIPLoaderGGUFMultiGPU
- logging.info(f"MultiGPU: Registered TripleCLIPLoaderGGUFMultiGPU")
-
- TripleCLIPLoaderGGUFDisTorchMultiGPU = override_class_with_distorch(TripleCLIPLoaderGGUF)
- NODE_CLASS_MAPPINGS["TripleCLIPLoaderGGUFDisTorchMultiGPU"] = TripleCLIPLoaderGGUFDisTorchMultiGPU
- logging.info(f"MultiGPU: Registered TripleCLIPLoaderGGUFDisTorchMultiGPU")
-
-def register_LTXVLoaderMultiGPU():
- global NODE_CLASS_MAPPINGS
-
- class LTXVLoader:
- @classmethod
- def INPUT_TYPES(s):
- return {
- "required": {
- "ckpt_name": (folder_paths.get_filename_list("checkpoints"),
- {"tooltip": "The name of the checkpoint (model) to load."}),
- "dtype": (["bfloat16", "float32"], {"default": "bfloat16"})
- }
- }
-
- RETURN_TYPES = ("MODEL", "VAE")
- RETURN_NAMES = ("model", "vae")
- FUNCTION = "load"
- CATEGORY = "lightricks/LTXV"
- TITLE = "LTXV Loader"
- OUTPUT_NODE = False
-
- def load(self, ckpt_name, dtype):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["LTXVLoader"]()
- return original_loader.load(ckpt_name, dtype)
- def _load_unet(self, load_device, offload_device, weights, num_latent_channels, dtype, config=None ):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["LTXVLoader"]()
- return original_loader._load_unet(load_device, offload_device, weights, num_latent_channels, dtype, config=None )
- def _load_vae(self, weights, config=None):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["LTXVLoader"]()
- return original_loader._load_vae(weights, config=None)
+if check_module_exists("ComfyUI-LTXVideo") or check_module_exists("comfyui-ltxvideo"):
NODE_CLASS_MAPPINGS["LTXVLoaderMultiGPU"] = override_class(LTXVLoader)
- logging.info(f"MultiGPU: Registered LTXVLoaderMultiGPU")
-
-def register_Florence2ModelLoaderMultiGPU():
- global NODE_CLASS_MAPPINGS
-
- class Florence2ModelLoader:
- @classmethod
- def INPUT_TYPES(s):
- return {"required": {
- "model": ([item.name for item in Path(folder_paths.models_dir, "LLM").iterdir() if item.is_dir()],
- {"tooltip": "models are expected to be in Comfyui/models/LLM folder"}),
- "precision": (['fp16','bf16','fp32'],),
- "attention": (['flash_attention_2', 'sdpa', 'eager'], {"default": 'sdpa'}),
- },
- "optional": {
- "lora": ("PEFTLORA",),
- }}
-
- RETURN_TYPES = ("FL2MODEL",)
- RETURN_NAMES = ("florence2_model",)
- FUNCTION = "loadmodel"
- CATEGORY = "Florence2"
-
- def loadmodel(self, model, precision, attention, lora=None):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["Florence2ModelLoader"]()
- return original_loader.loadmodel(model, precision, attention, lora)
- NODE_CLASS_MAPPINGS["Florence2ModelLoaderMultiGPU"] = override_class(Florence2ModelLoader)
- logging.info(f"MultiGPU: Registered Florence2ModelLoaderMultiGPU")
-
-def register_DownloadAndLoadFlorence2ModelMultiGPU():
- global NODE_CLASS_MAPPINGS
-
- class DownloadAndLoadFlorence2Model:
- @classmethod
- def INPUT_TYPES(s):
- return {"required": {
- "model": ([
- 'microsoft/Florence-2-base',
- 'microsoft/Florence-2-base-ft',
- 'microsoft/Florence-2-large',
- 'microsoft/Florence-2-large-ft',
- 'HuggingFaceM4/Florence-2-DocVQA',
- 'thwri/CogFlorence-2.1-Large',
- 'thwri/CogFlorence-2.2-Large',
- 'gokaygokay/Florence-2-SD3-Captioner',
- 'gokaygokay/Florence-2-Flux-Large',
- 'MiaoshouAI/Florence-2-base-PromptGen-v1.5',
- 'MiaoshouAI/Florence-2-large-PromptGen-v1.5',
- 'MiaoshouAI/Florence-2-base-PromptGen-v2.0',
- 'MiaoshouAI/Florence-2-large-PromptGen-v2.0'
- ], {"default": 'microsoft/Florence-2-base'}),
- "precision": (['fp16','bf16','fp32'], {"default": 'fp16'}),
- "attention": (['flash_attention_2', 'sdpa', 'eager'], {"default": 'sdpa'}),
- },
- "optional": {
- "lora": ("PEFTLORA",),
- }}
-
- RETURN_TYPES = ("FL2MODEL",)
- RETURN_NAMES = ("florence2_model",)
- FUNCTION = "loadmodel"
- CATEGORY = "Florence2"
-
- def loadmodel(self, model, precision, attention, lora=None):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["DownloadAndLoadFlorence2Model"]()
- return original_loader.loadmodel(model, precision, attention, lora)
- NODE_CLASS_MAPPINGS["DownloadAndLoadFlorence2ModelMultiGPU"] = override_class(DownloadAndLoadFlorence2Model)
- logging.info(f"MultiGPU: Registered DownloadAndLoadFlorence2ModelMultiGPU")
-
-def register_CheckpointLoaderNF4():
- global NODE_CLASS_MAPPINGS
-
- class CheckpointLoaderNF4:
- @classmethod
- def INPUT_TYPES(s):
- return {"required": { "ckpt_name": (folder_paths.get_filename_list("checkpoints"), ),
- }}
- RETURN_TYPES = ("MODEL", "CLIP", "VAE")
- FUNCTION = "load_checkpoint"
-
- CATEGORY = "loaders"
-
-
- def load_checkpoint(self, ckpt_name):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["CheckpointLoaderNF4"]()
- return original_loader.load_checkpoint(ckpt_name)
-
- NODE_CLASS_MAPPINGS["CheckpointLoaderNF4MultiGPU"] = override_class(CheckpointLoaderNF4)
- logging.info(f"MultiGPU: Registered CheckpointLoaderNF4MultiGPU")
-
-def register_LoadFluxControlNetMultiGPU():
- global NODE_CLASS_MAPPINGS
-
- class LoadFluxControlNet:
- @classmethod
- def INPUT_TYPES(s):
- return {"required": {"model_name": (["flux-dev", "flux-dev-fp8", "flux-schnell"],),
- "controlnet_path": (folder_paths.get_filename_list("xlabs_controlnets"), ),
- }}
-
- RETURN_TYPES = ("FluxControlNet",)
- RETURN_NAMES = ("ControlNet",)
- FUNCTION = "loadmodel"
- CATEGORY = "XLabsNodes"
-
- def loadmodel(self, model_name, controlnet_path):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["LoadFluxControlNet"]()
- return original_loader.loadmodel(model_name, controlnet_path)
-
- NODE_CLASS_MAPPINGS["LoadFluxControlNetMultiGPU"] = override_class(LoadFluxControlNet)
- logging.info(f"MultiGPU: Registered LoadFluxControlNetMultiGPU")
-
-def register_MMAudioModelLoaderMultiGPU():
-
- global NODE_CLASS_MAPPINGS
-
- class MMAudioModelLoader:
- @classmethod
- def INPUT_TYPES(s):
- return {
- "required": {
- "mmaudio_model": (folder_paths.get_filename_list("mmaudio"), {"tooltip": "These models are loaded from the 'ComfyUI/models/mmaudio' -folder",}),
-
- "base_precision": (["fp16", "fp32", "bf16"], {"default": "fp16"}),
- },
- }
-
- RETURN_TYPES = ("MMAUDIO_MODEL",)
- RETURN_NAMES = ("mmaudio_model", )
- FUNCTION = "loadmodel"
- CATEGORY = "MMAudio"
-
- def loadmodel(self, mmaudio_model, base_precision):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["MMAudioModelLoader"]()
- return original_loader.loadmodel(mmaudio_model, base_precision)
-
- NODE_CLASS_MAPPINGS["MMAudioModelLoaderMultiGPU"] = override_class(MMAudioModelLoader)
- logging.info(f"MultiGPU: Registered MMAudioModelLoaderMultiGPU")
-
-def register_MMAudioFeatureUtilsLoaderMultiGPU():
-
- global NODE_CLASS_MAPPINGS
-
-
- class MMAudioFeatureUtilsLoader:
- @classmethod
- def INPUT_TYPES(s):
- return {
- "required": {
- "vae_model": (folder_paths.get_filename_list("mmaudio"), {"tooltip": "These models are loaded from 'ComfyUI/models/mmaudio'"}),
- "synchformer_model": (folder_paths.get_filename_list("mmaudio"), {"tooltip": "These models are loaded from 'ComfyUI/models/mmaudio'"}),
- "clip_model": (folder_paths.get_filename_list("mmaudio"), {"tooltip": "These models are loaded from 'ComfyUI/models/mmaudio'"}),
- },
- "optional": {
- "bigvgan_vocoder_model": ("VOCODER_MODEL", {"tooltip": "These models are loaded from 'ComfyUI/models/mmaudio'"}),
- "mode": (["16k", "44k"], {"default": "44k"}),
- "precision": (["fp16", "fp32", "bf16"],
- {"default": "fp16"}
- ),
- }
- }
-
- RETURN_TYPES = ("MMAUDIO_FEATUREUTILS",)
- RETURN_NAMES = ("mmaudio_featureutils", )
- FUNCTION = "loadmodel"
- CATEGORY = "MMAudio"
-
- def loadmodel(self, vae_model, precision, synchformer_model, clip_model, mode, bigvgan_vocoder_model=None):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["MMAudioFeatureUtilsLoader"]()
- return original_loader.loadmodel(vae_model, precision, synchformer_model, clip_model, mode, bigvgan_vocoder_model)
-
- NODE_CLASS_MAPPINGS["MMAudioFeatureUtilsLoaderMultiGPU"] = override_class(MMAudioFeatureUtilsLoader)
- logging.info(f"MultiGPU: Registered MMAudioFeatureUtilsLoaderMultiGPU")
-
-def register_MMAudioSamplerMultiGPU():
-
- global NODE_CLASS_MAPPINGS
-
- class MMAudioSampler:
- @classmethod
- def INPUT_TYPES(s):
- return {
- "required": {
- "mmaudio_model": ("MMAUDIO_MODEL",),
- "feature_utils": ("MMAUDIO_FEATUREUTILS",),
- "duration": ("FLOAT", {"default": 8, "step": 0.01, "tooltip": "Duration of the audio in seconds"}),
- "steps": ("INT", {"default": 25, "step": 1, "tooltip": "Number of steps to interpolate"}),
- "cfg": ("FLOAT", {"default": 4.5, "step": 0.1, "tooltip": "Strength of the conditioning"}),
- "seed": ("INT", {"default": 0, "min": 0, "max": 0xffffffffffffffff}),
- "prompt": ("STRING", {"default": "", "multiline": True} ),
- "negative_prompt": ("STRING", {"default": "", "multiline": True} ),
- "mask_away_clip": ("BOOLEAN", {"default": False, "tooltip": "If true, the clip video will be masked away"}),
- "force_offload": ("BOOLEAN", {"default": True, "tooltip": "If true, the model will be offloaded to the offload device"}),
- },
- "optional": {
- "images": ("IMAGE",),
- },
- }
-
- RETURN_TYPES = ("AUDIO",)
- RETURN_NAMES = ("audio", )
- FUNCTION = "sample"
- CATEGORY = "MMAudio"
-
- def sample(self, mmaudio_model, seed, feature_utils, duration, steps, cfg, prompt, negative_prompt, mask_away_clip, force_offload, images=None):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["MMAudioSampler"]()
- return original_loader.sample(mmaudio_model, seed, feature_utils, duration, steps, cfg, prompt, negative_prompt, mask_away_clip, force_offload, images)
-
- NODE_CLASS_MAPPINGS["MMAudioSamplerMultiGPU"] = override_class(MMAudioSampler)
- logging.info(f"MultiGPU: Registered MMAudioSamplerMultiGPU")
-
-def register_PulidModelLoader():
-
- global NODE_CLASS_MAPPINGS
-
- class PulidModelLoader:
- @classmethod
- def INPUT_TYPES(s):
- return {"required": { "pulid_file": (folder_paths.get_filename_list("pulid"), )}}
-
- RETURN_TYPES = ("PULID",)
- FUNCTION = "load_model"
- CATEGORY = "pulid"
-
- def load_model(self, pulid_file):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["PulidModelLoader"]()
- return original_loader.load_model(pulid_file)
-
- NODE_CLASS_MAPPINGS["PulidModelLoaderMultiGPU"] = override_class(PulidModelLoader)
- logging.info(f"MultiGPU: Registered PulidModelLoaderMultiGPU")
-
-def register_PulidInsightFaceLoader():
-
- global NODE_CLASS_MAPPINGS
-
- class PulidInsightFaceLoader:
- @classmethod
- def INPUT_TYPES(s):
- return {
- "required": {
- "provider": (["CPU", "CUDA", "ROCM", "CoreML"], ),
- },
- }
-
- RETURN_TYPES = ("FACEANALYSIS",)
- FUNCTION = "load_insightface"
- CATEGORY = "pulid"
-
- def load_insightface(self, provider):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["PulidInsightFaceLoader"]()
- return original_loader.load_insightface(provider)
-
- NODE_CLASS_MAPPINGS["PulidInsightFaceLoaderMultiGPU"] = override_class(PulidInsightFaceLoader)
- logging.info(f"MultiGPU: Registered PulidInsightFaceLoaderMultiGPU")
-
-def register_PulidEvaClipLoader():
-
- global NODE_CLASS_MAPPINGS
-
- class PulidEvaClipLoader:
- @classmethod
- def INPUT_TYPES(s):
- return {
- "required": {},
- }
-
- RETURN_TYPES = ("EVA_CLIP",)
- FUNCTION = "load_eva_clip"
- CATEGORY = "pulid"
-
- def load_eva_clip(self):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["PulidEvaClipLoader"]()
- return original_loader.load_eva_clip()
-
- NODE_CLASS_MAPPINGS["PulidEvaClipLoaderMultiGPU"] = override_class(PulidEvaClipLoader)
- logging.info(f"MultiGPU: Registered PulidEvaClipLoaderMultiGPU")
-
-def register_HyVideoModelLoader():
- global NODE_CLASS_MAPPINGS
-
- # Keep original MultiGPU wrapper unchanged
- class HyVideoModelLoader:
- @classmethod
- def INPUT_TYPES(s):
- return {
- "required": {
- "model": (folder_paths.get_filename_list("diffusion_models"), {"tooltip": "These models are loaded from the 'ComfyUI/models/diffusion_models' -folder",}),
- "base_precision": (["fp32", "bf16"], {"default": "bf16"}),
- "quantization": (['disabled', 'fp8_e4m3fn', 'fp8_e4m3fn_fast', 'fp8_scaled', 'torchao_fp8dq', "torchao_fp8dqrow", "torchao_int8dq", "torchao_fp6", "torchao_int4", "torchao_int8"], {"default": 'disabled', "tooltip": "optional quantization method"}),
- "load_device": (["main_device"], {"default": "main_device"}),
- },
- "optional": {
- "attention_mode": ([
- "sdpa",
- "flash_attn_varlen",
- "sageattn_varlen",
- "comfy",
- ], {"default": "flash_attn"}),
- "compile_args": ("COMPILEARGS", ),
- "block_swap_args": ("BLOCKSWAPARGS", ),
- "lora": ("HYVIDLORA", {"default": None}),
- "auto_cpu_offload": ("BOOLEAN", {"default": False, "tooltip": "Enable auto offloading for reduced VRAM usage, implementation from DiffSynth-Studio, slightly different from block swapping and uses even less VRAM, but can be slower as you can't define how much VRAM to use"}),
- }
- }
-
- RETURN_TYPES = ("HYVIDEOMODEL",)
- RETURN_NAMES = ("model", )
- FUNCTION = "loadmodel"
- CATEGORY = "HunyuanVideoWrapper"
-
- def loadmodel(self, model, base_precision, load_device, quantization, compile_args=None, attention_mode="sdpa", block_swap_args=None, lora=None, auto_cpu_offload=False):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["HyVideoModelLoader"]()
- return original_loader.loadmodel(model, base_precision, load_device, quantization, compile_args, attention_mode, block_swap_args, lora, auto_cpu_offload)
-
- NODE_CLASS_MAPPINGS["HyVideoModelLoaderMultiGPU"] = override_class(HyVideoModelLoader)
-
- logging.info(f"MultiGPU: Registered HyVideoModelLoader nodes")
-
-def register_HyVideoVAELoader():
-
- global NODE_CLASS_MAPPINGS
-
- class HyVideoVAELoader:
- @classmethod
- def INPUT_TYPES(s):
- return {
- "required": {
- "model_name": (folder_paths.get_filename_list("vae"), {"tooltip": "These models are loaded from 'ComfyUI/models/vae'"}),
- },
- "optional": {
- "precision": (["fp16", "fp32", "bf16"],
- {"default": "bf16"}
- ),
- "compile_args":("COMPILEARGS", ),
- }
- }
-
- RETURN_TYPES = ("VAE",)
- RETURN_NAMES = ("vae", )
- FUNCTION = "loadmodel"
- CATEGORY = "HunyuanVideoWrapper"
- DESCRIPTION = "Loads Hunyuan VAE model from 'ComfyUI/models/vae'"
-
- def loadmodel(self, model_name, precision, compile_args=None):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["HyVideoVAELoader"]()
- return original_loader.loadmodel(model_name, precision, compile_args)
-
- NODE_CLASS_MAPPINGS["HyVideoVAELoaderMultiGPU"] = override_class(HyVideoVAELoader)
- logging.info(f"MultiGPU: Registered HyVideoVAELoaderMultiGPU")
-
-def register_DownloadAndLoadHyVideoTextEncoder():
-
- global NODE_CLASS_MAPPINGS
-
- class DownloadAndLoadHyVideoTextEncoder:
- @classmethod
- def INPUT_TYPES(s):
- return {
- "required": {
- "llm_model": (["Kijai/llava-llama-3-8b-text-encoder-tokenizer","xtuner/llava-llama-3-8b-v1_1-transformers"],),
- "clip_model": (["disabled","openai/clip-vit-large-patch14",],),
- "precision": (["fp16", "fp32", "bf16"],
- {"default": "bf16"}
- ),
- },
- "optional": {
- "apply_final_norm": ("BOOLEAN", {"default": False}),
- "hidden_state_skip_layer": ("INT", {"default": 2}),
- "quantization": (['disabled', 'bnb_nf4', "fp8_e4m3fn"], {"default": 'disabled'}),
- }
- }
-
- RETURN_TYPES = ("HYVIDTEXTENCODER",)
- RETURN_NAMES = ("hyvid_text_encoder", )
- FUNCTION = "loadmodel"
- CATEGORY = "HunyuanVideoWrapper"
- DESCRIPTION = "Loads Hunyuan text_encoder model from 'ComfyUI/models/LLM'"
-
- def loadmodel(self, llm_model, clip_model, precision, apply_final_norm=False, hidden_state_skip_layer=2, quantization="disabled"):
- from nodes import NODE_CLASS_MAPPINGS
- original_loader = NODE_CLASS_MAPPINGS["DownloadAndLoadHyVideoTextEncoder"]()
- return original_loader.loadmodel(llm_model, clip_model, precision, apply_final_norm, hidden_state_skip_layer, quantization)
-
- NODE_CLASS_MAPPINGS["DownloadAndLoadHyVideoTextEncoderMultiGPU"] = override_class(DownloadAndLoadHyVideoTextEncoder)
- logging.info(f"MultiGPU: Registered DownloadAndLoadHyVideoTextEncoderMultiGPU")
-
-# Register desired nodes
-register_module(["UNETLoader", "VAELoader", "CLIPLoader", "DualCLIPLoader", "TripleCLIPLoader", "CheckpointLoaderSimple", "ControlNetLoader"])
-if check_module_exists("ComfyUI-LTXVideo") or check_module_exists("comfyui-ltxvideo"):
- register_LTXVLoaderMultiGPU()
if check_module_exists("ComfyUI-Florence2") or check_module_exists("comfyui-florence2"):
- register_Florence2ModelLoaderMultiGPU()
- register_DownloadAndLoadFlorence2ModelMultiGPU()
-if check_module_exists("ComfyUI_bitsandbytes_NF4") or check_module_exists("comfyui_bitsandbytes_nf4"):
- register_CheckpointLoaderNF4()
-if check_module_exists("x-flux-comfyui") or check_module_exists("x-flux-comfyui"):
- register_LoadFluxControlNetMultiGPU()
-if check_module_exists("ComfyUI-MMAudio") or check_module_exists("comfyui-mmaudio"):
- register_MMAudioModelLoaderMultiGPU()
- register_MMAudioFeatureUtilsLoaderMultiGPU()
- register_MMAudioSamplerMultiGPU()
-if check_module_exists("ComfyUI-GGUF") or check_module_exists("comfyui-gguf"):
- register_UnetLoaderGGUFMultiGPU()
- register_CLIPLoaderGGUFMultiGPU()
-if check_module_exists("PuLID_ComfyUI") or check_module_exists("pulid_comfyui"):
- register_PulidModelLoader()
- register_PulidInsightFaceLoader()
- register_PulidEvaClipLoader()
-if check_module_exists("ComfyUI-HunyuanVideoWrapper") or check_module_exists("comfyui-hunyuanvideowrapper"):
- register_HyVideoModelLoader()
- register_HyVideoVAELoader()
- register_DownloadAndLoadHyVideoTextEncoder()
+ NODE_CLASS_MAPPINGS["Florence2ModelLoaderMultiGPU"] = override_class(Florence2ModelLoader)
+ NODE_CLASS_MAPPINGS["DownloadAndLoadFlorence2ModelMultiGPU"] = override_class(DownloadAndLoadFlorence2Model)
+if check_module_exists("ComfyUI_bitsandbytes_NF4") or check_module_exists("comfyui_bitsandbytes_nf4"):
+ NODE_CLASS_MAPPINGS["CheckpointLoaderNF4MultiGPU"] = override_class(CheckpointLoaderNF4)
+
+if check_module_exists("x-flux-comfyui") or check_module_exists("x-flux-comfyui"):
+ NODE_CLASS_MAPPINGS["LoadFluxControlNetMultiGPU"] = override_class(LoadFluxControlNet)
+
+if check_module_exists("ComfyUI-MMAudio") or check_module_exists("comfyui-mmaudio"):
+ NODE_CLASS_MAPPINGS["MMAudioModelLoaderMultiGPU"] = override_class(MMAudioModelLoader)
+ NODE_CLASS_MAPPINGS["MMAudioFeatureUtilsLoaderMultiGPU"] = override_class(MMAudioFeatureUtilsLoader)
+ NODE_CLASS_MAPPINGS["MMAudioSamplerMultiGPU"] = override_class(MMAudioSampler)
+
+if check_module_exists("ComfyUI-GGUF") or check_module_exists("comfyui-gguf"):
+ NODE_CLASS_MAPPINGS["UnetLoaderGGUFMultiGPU"] = override_class(UnetLoaderGGUF)
+ NODE_CLASS_MAPPINGS["UnetLoaderGGUFDisTorchMultiGPU"] = override_class_with_distorch(UnetLoaderGGUF)
+ NODE_CLASS_MAPPINGS["UnetLoaderGGUFAdvancedMultiGPU"] = override_class(UnetLoaderGGUFAdvanced)
+ NODE_CLASS_MAPPINGS["UnetLoaderGGUFAdvancedDisTorchMultiGPU"] = override_class_with_distorch(UnetLoaderGGUFAdvanced)
+ NODE_CLASS_MAPPINGS["CLIPLoaderGGUFMultiGPU"] = override_class(CLIPLoaderGGUF)
+ NODE_CLASS_MAPPINGS["CLIPLoaderGGUFDisTorchMultiGPU"] = override_class_with_distorch(CLIPLoaderGGUF)
+ NODE_CLASS_MAPPINGS["DualCLIPLoaderGGUFMultiGPU"] = override_class(DualCLIPLoaderGGUF)
+ NODE_CLASS_MAPPINGS["DualCLIPLoaderGGUFDisTorchMultiGPU"] = override_class_with_distorch(DualCLIPLoaderGGUF)
+ NODE_CLASS_MAPPINGS["TripleCLIPLoaderGGUFMultiGPU"] = override_class(TripleCLIPLoaderGGUF)
+ NODE_CLASS_MAPPINGS["TripleCLIPLoaderGGUFDisTorchMultiGPU"] = override_class_with_distorch(TripleCLIPLoaderGGUF)
+
+if check_module_exists("PuLID_ComfyUI") or check_module_exists("pulid_comfyui"):
+ NODE_CLASS_MAPPINGS["PulidModelLoaderMultiGPU"] = override_class(PulidModelLoader)
+ NODE_CLASS_MAPPINGS["PulidInsightFaceLoaderMultiGPU"] = override_class(PulidInsightFaceLoader)
+ NODE_CLASS_MAPPINGS["PulidEvaClipLoaderMultiGPU"] = override_class(PulidEvaClipLoader)
+
+if check_module_exists("ComfyUI-HunyuanVideoWrapper") or check_module_exists("comfyui-hunyuanvideowrapper"):
+ NODE_CLASS_MAPPINGS["HyVideoModelLoaderMultiGPU"] = override_class(HyVideoModelLoader)
+ NODE_CLASS_MAPPINGS["HyVideoVAELoaderMultiGPU"] = override_class(HyVideoVAELoader)
+ NODE_CLASS_MAPPINGS["DownloadAndLoadHyVideoTextEncoderMultiGPU"] = override_class(DownloadAndLoadHyVideoTextEncoder)
logging.info(f"MultiGPU: Registration complete. Final mappings: {', '.join(NODE_CLASS_MAPPINGS.keys())}")
diff --git a/assets/distorch2_0.gif b/assets/distorch2_0.gif
old mode 100644
new mode 100755
diff --git a/assets/distorch2_0.png b/assets/distorch2_0.png
old mode 100644
new mode 100755
diff --git a/assets/distorch_average.png b/assets/distorch_average.png
old mode 100644
new mode 100755
diff --git a/assets/distorch_node.png b/assets/distorch_node.png
old mode 100644
new mode 100755
diff --git a/binaries/linux/rename_this_to_keep_user_binary.txt b/binaries/linux/rename_this_to_keep_user_binary.txt
new file mode 100644
index 0000000..e69de29
diff --git a/examples/flux1dev_gguf_distorch.json b/examples/flux1dev_gguf_distorch.json
old mode 100644
new mode 100755
index 5bb0145..bec502f
--- a/examples/flux1dev_gguf_distorch.json
+++ b/examples/flux1dev_gguf_distorch.json
@@ -14,7 +14,7 @@
46
],
"flags": {},
- "order": 10,
+ "order": 8,
"mode": 0,
"inputs": [
{
@@ -90,7 +90,7 @@
387.28668212890625
],
"flags": {},
- "order": 11,
+ "order": 9,
"mode": 0,
"inputs": [
{
@@ -158,7 +158,7 @@
692.112548828125
],
"flags": {},
- "order": 13,
+ "order": 11,
"mode": 0,
"inputs": [
{
@@ -187,7 +187,7 @@
200
],
"flags": {},
- "order": 8,
+ "order": 7,
"mode": 0,
"inputs": [
{
@@ -213,79 +213,6 @@
"A towering technological monolith in a cyberpunk cityscape at night, with \"DisTorch\" emblazoned across its surface in massive neon red letters that illuminate the surrounding buildings. The text occupies the central third of the frame, crafted from glowing plasma tubes and crackling energy. Rain-slicked streets below reflect the brilliant signage, while holographic advertisements and flying vehicles populate the background. Moody atmospheric lighting, heavy contrast, photorealistic textures, cinematic color grading."
]
},
- {
- "id": 35,
- "type": "DualCLIPLoaderGGUFMultiGPU",
- "pos": [
- -74.29531860351562,
- 272.3004455566406
- ],
- "size": [
- 435.3804016113281,
- 130
- ],
- "flags": {},
- "order": 1,
- "mode": 0,
- "inputs": [],
- "outputs": [
- {
- "name": "CLIP",
- "type": "CLIP",
- "links": [
- 99
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "DualCLIPLoaderGGUFMultiGPU"
- },
- "widgets_values": [
- "t5-v1_1-xxl-encoder-Q4_K_M.gguf",
- "clip_l.safetensors",
- "flux",
- "cuda:1"
- ],
- "color": "#233",
- "bgcolor": "#355"
- },
- {
- "id": 33,
- "type": "VAELoaderMultiGPU",
- "pos": [
- -62.57144546508789,
- 460.42584228515625
- ],
- "size": [
- 450.23980712890625,
- 82
- ],
- "flags": {},
- "order": 2,
- "mode": 0,
- "inputs": [],
- "outputs": [
- {
- "name": "VAE",
- "type": "VAE",
- "links": [
- 84
- ],
- "slot_index": 0,
- "shape": 3
- }
- ],
- "properties": {
- "Node name for S&R": "VAELoaderMultiGPU"
- },
- "widgets_values": [
- "ae.safetensors",
- "cuda:1"
- ],
- "color": "#233",
- "bgcolor": "#355"
- },
{
"id": 17,
"type": "BasicScheduler",
@@ -298,7 +225,7 @@
106
],
"flags": {},
- "order": 9,
+ "order": 6,
"mode": 0,
"inputs": [
{
@@ -339,7 +266,7 @@
46
],
"flags": {},
- "order": 12,
+ "order": 10,
"mode": 0,
"inputs": [
{
@@ -368,43 +295,6 @@
},
"widgets_values": []
},
- {
- "id": 37,
- "type": "UnetLoaderGGUFDisTorchMultiGPU",
- "pos": [
- -71.38706970214844,
- 90.67648315429688
- ],
- "size": [
- 417.6407775878906,
- 124
- ],
- "flags": {},
- "order": 3,
- "mode": 0,
- "inputs": [],
- "outputs": [
- {
- "name": "MODEL",
- "type": "MODEL",
- "links": [
- 102,
- 103
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "UnetLoaderGGUFDisTorchMultiGPU"
- },
- "widgets_values": [
- "flux1-dev-Q8_0.gguf",
- "cuda:0",
- "cuda:0,0.4608;cuda:1,0.0271;cpu,0.0136"
- ],
- "color": "#233",
- "bgcolor": "#355"
- },
{
"id": 39,
"type": "EmptySD3LatentImage",
@@ -417,7 +307,7 @@
106
],
"flags": {},
- "order": 4,
+ "order": 1,
"mode": 0,
"inputs": [],
"outputs": [
@@ -439,30 +329,6 @@
1
]
},
- {
- "id": 52,
- "type": "Note",
- "pos": [
- -577.845458984375,
- 64.50007629394531
- ],
- "size": [
- 495.7899169921875,
- 484.21075439453125
- ],
- "flags": {},
- "order": 5,
- "mode": 0,
- "inputs": [],
- "outputs": [],
- "title": "How the DisTorch allocation string works",
- "properties": {},
- "widgets_values": [
- "The allocation string uses a semicolon (;) to separate device allocations, and each device allocation has two parts separated by a comma:\n\nDevice name (e.g., \"cuda:0\", \"cuda:1\", \"cpu\")\nMemory fraction as a decimal (e.g., 0.025 = 2.5%, 0.05 = 5%, 0.10 = 10%)\n\n\nFor my defaults:\n\nCUDA GPU 0: Will allocate 2.5% of its total available memory\nCUDA GPU 1: Will allocate 5% of its total available memory\nCPU: Will allocate 10% of available system memory\n\n\nDisTorch then:\n\nCalculates how much actual memory this means for each device\nDistributes model layers across devices proportionally based on these allocations\nAssigns layers to minimize memory usage while maintaining model functionality\n\n\n\nSo if you have a model with 100 layers and your GPUs have the following memory:\n\nCUDA:0 has 24GB\nCUDA:1 has 24GB\nSystem has 64GB RAM\n\nThe allocation would be:\n\nCUDA:0: 600MB (2.5% of 24GB)\nCUDA:1: 1.2GB (5% of 24GB)\nCPU: 6.4GB (10% of 64GB)\n\nThis would help manage memory usage across your devices while keeping the model functional. The semicolon-separated format makes it easy to specify different allocations for different devices in a single string."
- ],
- "color": "#233",
- "bgcolor": "#355"
- },
{
"id": 25,
"type": "RandomNoise",
@@ -475,7 +341,7 @@
88.84210968017578
],
"flags": {},
- "order": 6,
+ "order": 2,
"mode": 0,
"inputs": [],
"outputs": [
@@ -497,34 +363,113 @@
]
},
{
- "id": 34,
- "type": "UnetLoaderGGUFMultiGPU",
+ "id": 37,
+ "type": "UnetLoaderGGUFDisTorchMultiGPU",
"pos": [
- -79.20733642578125,
- -116.61892700195312
+ -71.38706970214844,
+ 90.67648315429688
],
"size": [
- 417.5072937011719,
- 97.88888549804688
+ 417.6407775878906,
+ 154
],
"flags": {},
- "order": 7,
- "mode": 4,
+ "order": 3,
+ "mode": 0,
"inputs": [],
"outputs": [
{
"name": "MODEL",
"type": "MODEL",
- "links": [],
+ "links": [
+ 102,
+ 103
+ ],
"slot_index": 0
}
],
"properties": {
- "Node name for S&R": "UnetLoaderGGUFMultiGPU"
+ "Node name for S&R": "UnetLoaderGGUFDisTorchMultiGPU"
},
"widgets_values": [
"flux1-dev-Q8_0.gguf",
- "cuda:0"
+ "cuda:0",
+ 6,
+ false,
+ ""
+ ],
+ "color": "#233",
+ "bgcolor": "#355"
+ },
+ {
+ "id": 33,
+ "type": "VAELoaderMultiGPU",
+ "pos": [
+ -66.57144165039062,
+ 479.7591552734375
+ ],
+ "size": [
+ 450.23980712890625,
+ 82
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "VAE",
+ "type": "VAE",
+ "links": [
+ 84
+ ],
+ "slot_index": 0,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VAELoaderMultiGPU"
+ },
+ "widgets_values": [
+ "ae.safetensors",
+ "cuda:1"
+ ],
+ "color": "#233",
+ "bgcolor": "#355"
+ },
+ {
+ "id": 35,
+ "type": "DualCLIPLoaderGGUFMultiGPU",
+ "pos": [
+ -69.62869262695312,
+ 285.6338195800781
+ ],
+ "size": [
+ 435.3804016113281,
+ 130
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "CLIP",
+ "type": "CLIP",
+ "links": [
+ 99
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "DualCLIPLoaderGGUFMultiGPU"
+ },
+ "widgets_values": [
+ "t5-v1_1-xxl-encoder-Q4_K_M.gguf",
+ "clip_l.safetensors",
+ "flux",
+ "cuda:1"
],
"color": "#233",
"bgcolor": "#355"
@@ -632,10 +577,10 @@
"config": {},
"extra": {
"ds": {
- "scale": 0.8769226950001245,
+ "scale": 1,
"offset": [
- 955.3126283315189,
- 498.64012539888034
+ 574.0015045555798,
+ 267.12195585438565
]
},
"ue_links": [],
@@ -644,7 +589,9 @@
"node_versions": {
"comfy-core": "0.3.12",
"ComfyUI-MultiGPU": "3dbfcc713552b0560a471c10d9b29520e8b1981e"
- }
+ },
+ "VHS_MetadataImage": true,
+ "VHS_KeepIntermediate": true
},
"version": 0.4
}
\ No newline at end of file
diff --git a/examples/hunyuan_gguf_distorch.json b/examples/hunyuan_gguf_distorch.json
old mode 100644
new mode 100755
index 048c9ce..68f6bd1
--- a/examples/hunyuan_gguf_distorch.json
+++ b/examples/hunyuan_gguf_distorch.json
@@ -1,6 +1,6 @@
{
- "last_node_id": 119,
- "last_link_id": 155,
+ "last_node_id": 120,
+ "last_link_id": 156,
"nodes": [
{
"id": 72,
@@ -14,7 +14,7 @@
58
],
"flags": {},
- "order": 11,
+ "order": 10,
"mode": 0,
"inputs": [
{
@@ -55,7 +55,7 @@
58
],
"flags": {},
- "order": 9,
+ "order": 7,
"mode": 0,
"inputs": [
{
@@ -93,7 +93,7 @@
150
],
"flags": {},
- "order": 14,
+ "order": 13,
"mode": 0,
"inputs": [
{
@@ -127,76 +127,6 @@
8
]
},
- {
- "id": 75,
- "type": "SamplerCustomAdvanced",
- "pos": [
- 3488.497314453125,
- -150.8239288330078
- ],
- "size": [
- 292.4319763183594,
- 479.03521728515625
- ],
- "flags": {
- "collapsed": false
- },
- "order": 13,
- "mode": 0,
- "inputs": [
- {
- "name": "noise",
- "type": "NOISE",
- "link": 87,
- "slot_index": 0
- },
- {
- "name": "guider",
- "type": "GUIDER",
- "link": 88,
- "slot_index": 1
- },
- {
- "name": "sampler",
- "type": "SAMPLER",
- "link": 89,
- "slot_index": 2
- },
- {
- "name": "sigmas",
- "type": "SIGMAS",
- "link": 90,
- "slot_index": 3
- },
- {
- "name": "latent_image",
- "type": "LATENT",
- "link": 155,
- "slot_index": 4
- }
- ],
- "outputs": [
- {
- "name": "output",
- "type": "LATENT",
- "links": [
- 85
- ],
- "slot_index": 0,
- "shape": 3
- },
- {
- "name": "denoised_output",
- "type": "LATENT",
- "links": null,
- "shape": 3
- }
- ],
- "properties": {
- "Node name for S&R": "SamplerCustomAdvanced"
- },
- "widgets_values": []
- },
{
"id": 66,
"type": "BasicScheduler",
@@ -209,7 +139,7 @@
109.8011474609375
],
"flags": {},
- "order": 10,
+ "order": 8,
"mode": 0,
"inputs": [
{
@@ -270,41 +200,6 @@
"euler"
]
},
- {
- "id": 76,
- "type": "VAELoaderMultiGPU",
- "pos": [
- 2629.39599609375,
- 275.80596923828125
- ],
- "size": [
- 341.07464599609375,
- 87.14057922363281
- ],
- "flags": {},
- "order": 1,
- "mode": 0,
- "inputs": [],
- "outputs": [
- {
- "name": "VAE",
- "type": "VAE",
- "links": [
- 99
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "VAELoaderMultiGPU"
- },
- "widgets_values": [
- "hunyuan_video_vae_bf16.safetensors",
- "cuda:1"
- ],
- "color": "#233",
- "bgcolor": "#355"
- },
{
"id": 115,
"type": "EmptyHunyuanLatentVideo",
@@ -319,7 +214,7 @@
"flags": {
"collapsed": false
},
- "order": 2,
+ "order": 1,
"mode": 0,
"inputs": [],
"outputs": [
@@ -354,7 +249,7 @@
190.77996826171875
],
"flags": {},
- "order": 3,
+ "order": 2,
"mode": 0,
"inputs": [],
"outputs": [],
@@ -378,7 +273,7 @@
82
],
"flags": {},
- "order": 4,
+ "order": 3,
"mode": 0,
"inputs": [],
"outputs": [
@@ -413,7 +308,7 @@
902.6787109375
],
"flags": {},
- "order": 15,
+ "order": 14,
"mode": 0,
"inputs": [
{
@@ -465,13 +360,13 @@
"hidden": false,
"paused": false,
"params": {
- "filename": "HunyuanVideo_00315.mp4",
+ "filename": "HunyuanVideo_00336.mp4",
"subfolder": "",
"type": "output",
"format": "video/h264-mp4",
"frame_rate": 24,
- "workflow": "HunyuanVideo_00315.png",
- "fullpath": "/home/johnj/ComfyUI/output/HunyuanVideo_00315.mp4"
+ "workflow": "HunyuanVideo_00336.png",
+ "fullpath": "/home/johnj/ComfyUI/output/HunyuanVideo_00336.mp4"
},
"muted": false
}
@@ -491,7 +386,7 @@
"flags": {
"collapsed": true
},
- "order": 12,
+ "order": 11,
"mode": 0,
"inputs": [
{
@@ -523,30 +418,6 @@
},
"widgets_values": []
},
- {
- "id": 119,
- "type": "Note",
- "pos": [
- 2050.9873046875,
- -145.64498901367188
- ],
- "size": [
- 549.7151489257812,
- 528.065185546875
- ],
- "flags": {},
- "order": 5,
- "mode": 0,
- "inputs": [],
- "outputs": [],
- "title": "How the DisTorch allocation string works",
- "properties": {},
- "widgets_values": [
- "The allocation string uses a semicolon (;) to separate device allocations, and each device allocation has two parts separated by a comma:\n\nDevice name (e.g., \"cuda:0\", \"cuda:1\", \"cpu\")\nMemory fraction as a decimal (e.g., 0.025 = 2.5%, 0.05 = 5%, 0.10 = 10%)\n\n\nFor my defaults:\n\nCUDA GPU 0: Will allocate 2.5% of its total available memory\nCUDA GPU 1: Will allocate 5% of its total available memory\nCPU: Will allocate 10% of available system memory\n\n\nDisTorch then:\n\nCalculates how much actual memory this means for each device\nDistributes model layers across devices proportionally based on these allocations\nAssigns layers to minimize memory usage while maintaining model functionality\n\n\n\nSo if you have a model with 100 layers and your GPUs have the following memory:\n\nCUDA:0 has 24GB\nCUDA:1 has 24GB\nSystem has 64GB RAM\n\nThe allocation would be:\n\nCUDA:0: 600MB (2.5% of 24GB)\nCUDA:1: 1.2GB (5% of 24GB)\nCPU: 6.4GB (10% of 64GB)\n\nThis would help manage memory usage across your devices while keeping the model functional. The semicolon-separated format makes it easy to specify different allocations for different devices in a single string."
- ],
- "color": "#233",
- "bgcolor": "#355"
- },
{
"id": 67,
"type": "CLIPTextEncode",
@@ -559,13 +430,13 @@
164.31304931640625
],
"flags": {},
- "order": 8,
+ "order": 9,
"mode": 0,
"inputs": [
{
"name": "clip",
"type": "CLIP",
- "link": 154
+ "link": 156
}
],
"outputs": [
@@ -589,56 +460,123 @@
"bgcolor": "#353"
},
{
- "id": 100,
- "type": "DualCLIPLoaderGGUFDisTorchMultiGPU",
+ "id": 76,
+ "type": "VAELoaderMultiGPU",
"pos": [
- 2623.7119140625,
- 64.39619445800781
+ 2632.252685546875,
+ 327.2115783691406
],
"size": [
- 348.5331726074219,
- 154
+ 341.07464599609375,
+ 87.14057922363281
],
"flags": {},
- "order": 6,
+ "order": 4,
"mode": 0,
"inputs": [],
"outputs": [
{
- "name": "CLIP",
- "type": "CLIP",
+ "name": "VAE",
+ "type": "VAE",
"links": [
- 154
+ 99
],
"slot_index": 0
}
],
"properties": {
- "Node name for S&R": "DualCLIPLoaderGGUFDisTorchMultiGPU"
+ "Node name for S&R": "VAELoaderMultiGPU"
},
"widgets_values": [
- "clip_l.safetensors",
- "llava-llama-3-8B-v1_1-Q4_K_M.gguf",
- "hunyuan_video",
- "cuda:1",
- "cuda:1,0.33;cpu,0.15"
+ "hunyuan_video_vae_bf16.safetensors",
+ "cuda:1"
],
"color": "#233",
"bgcolor": "#355"
},
+ {
+ "id": 75,
+ "type": "SamplerCustomAdvanced",
+ "pos": [
+ 3517.626953125,
+ -117.69574737548828
+ ],
+ "size": [
+ 292.4319763183594,
+ 479.03521728515625
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 12,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "noise",
+ "type": "NOISE",
+ "link": 87,
+ "slot_index": 0
+ },
+ {
+ "name": "guider",
+ "type": "GUIDER",
+ "link": 88,
+ "slot_index": 1
+ },
+ {
+ "name": "sampler",
+ "type": "SAMPLER",
+ "link": 89,
+ "slot_index": 2
+ },
+ {
+ "name": "sigmas",
+ "type": "SIGMAS",
+ "link": 90,
+ "slot_index": 3
+ },
+ {
+ "name": "latent_image",
+ "type": "LATENT",
+ "link": 155,
+ "slot_index": 4
+ }
+ ],
+ "outputs": [
+ {
+ "name": "output",
+ "type": "LATENT",
+ "links": [
+ 85
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "denoised_output",
+ "type": "LATENT",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "SamplerCustomAdvanced"
+ },
+ "widgets_values": []
+ },
{
"id": 88,
"type": "UnetLoaderGGUFDisTorchMultiGPU",
"pos": [
- 2622.552734375,
- -105.02156829833984
+ 2624.267822265625,
+ -66.1816177368164
],
"size": [
358.005859375,
- 128.5614013671875
+ 154
],
"flags": {},
- "order": 7,
+ "order": 5,
"mode": 0,
"inputs": [],
"outputs": [
@@ -656,9 +594,48 @@
"Node name for S&R": "UnetLoaderGGUFDisTorchMultiGPU"
},
"widgets_values": [
- "flux1-dev-Q8_0.gguf",
+ "hunyuan-video-t2v-720p-Q8_0.gguf",
"cuda:0",
- "cuda:0,0.33;cuda:1,0.33;cpu,0.0825"
+ 8,
+ false,
+ ""
+ ],
+ "color": "#233",
+ "bgcolor": "#355"
+ },
+ {
+ "id": 120,
+ "type": "DualCLIPLoaderGGUFMultiGPU",
+ "pos": [
+ 2625.07763671875,
+ 132.1048126220703
+ ],
+ "size": [
+ 348.16229248046875,
+ 130
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "CLIP",
+ "type": "CLIP",
+ "links": [
+ 156
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "DualCLIPLoaderGGUFMultiGPU"
+ },
+ "widgets_values": [
+ "clip_l.safetensors",
+ "llava-llama-3-8B-v1_1-Q4_K_M.gguf",
+ "hunyuan_video",
+ "cpu"
],
"color": "#233",
"bgcolor": "#355"
@@ -761,14 +738,6 @@
0,
"MODEL"
],
- [
- 154,
- 100,
- 0,
- 67,
- 0,
- "CLIP"
- ],
[
155,
115,
@@ -776,6 +745,14 @@
75,
4,
"LATENT"
+ ],
+ [
+ 156,
+ 120,
+ 0,
+ 67,
+ 0,
+ "CLIP"
]
],
"groups": [
@@ -783,8 +760,8 @@
"id": 1,
"title": "GGUFDisTorchMultiGPU",
"bounding": [
- 2617.71240234375,
- -173.0873565673828,
+ 2620.569091796875,
+ -121.6815185546875,
360.4816589355469,
537.903076171875
],
@@ -796,15 +773,17 @@
"config": {},
"extra": {
"ds": {
- "scale": 1.283902517749697,
+ "scale": 1.167184107045179,
"offset": [
- -2107.057728768135,
- 344.093734201536
+ -2360.0515813693187,
+ 465.0591039206934
]
},
"ue_links": [],
"VHS_latentpreview": false,
- "VHS_latentpreviewrate": 0
+ "VHS_latentpreviewrate": 0,
+ "VHS_MetadataImage": true,
+ "VHS_KeepIntermediate": true
},
"version": 0.4
}
\ No newline at end of file
diff --git a/examples/hunyuan_ip2v_distorch_gguf.json b/examples/hunyuan_ip2v_distorch_gguf.json
old mode 100644
new mode 100755
index 3809e4a..01b44bb
--- a/examples/hunyuan_ip2v_distorch_gguf.json
+++ b/examples/hunyuan_ip2v_distorch_gguf.json
@@ -159,7 +159,7 @@
452.87860107421875
],
"flags": {},
- "order": 10,
+ "order": 8,
"mode": 0,
"inputs": [
{
@@ -219,43 +219,6 @@
""
]
},
- {
- "id": 115,
- "type": "UnetLoaderGGUFDisTorchMultiGPU",
- "pos": [
- -807.809814453125,
- 227.3965301513672
- ],
- "size": [
- 342.1245422363281,
- 106
- ],
- "flags": {},
- "order": 2,
- "mode": 0,
- "inputs": [],
- "outputs": [
- {
- "name": "MODEL",
- "type": "MODEL",
- "links": [
- 276,
- 277
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "UnetLoaderGGUFDisTorchMultiGPU"
- },
- "widgets_values": [
- "hunyuan-video-t2v-720p-Q8_0.gguf",
- "cuda:0",
- "cuda:0,0.15;cpu,0.5"
- ],
- "color": "#233",
- "bgcolor": "#355"
- },
{
"id": 112,
"type": "LoadImage",
@@ -268,7 +231,7 @@
314
],
"flags": {},
- "order": 3,
+ "order": 2,
"mode": 0,
"inputs": [],
"outputs": [
@@ -306,7 +269,7 @@
190.77996826171875
],
"flags": {},
- "order": 4,
+ "order": 3,
"mode": 0,
"inputs": [],
"outputs": [],
@@ -332,7 +295,7 @@
"flags": {
"collapsed": true
},
- "order": 8,
+ "order": 9,
"mode": 0,
"inputs": [
{
@@ -372,7 +335,7 @@
"flags": {
"collapsed": true
},
- "order": 9,
+ "order": 10,
"mode": 0,
"inputs": [
{
@@ -540,7 +503,7 @@
"flags": {
"collapsed": true
},
- "order": 5,
+ "order": 4,
"mode": 0,
"inputs": [],
"outputs": [
@@ -572,7 +535,7 @@
130
],
"flags": {},
- "order": 6,
+ "order": 5,
"mode": 0,
"inputs": [],
"outputs": [
@@ -595,41 +558,6 @@
1
]
},
- {
- "id": 25,
- "type": "RandomNoise",
- "pos": [
- 389.7550354003906,
- -21.38304328918457
- ],
- "size": [
- 250.37998962402344,
- 82
- ],
- "flags": {},
- "order": 7,
- "mode": 0,
- "inputs": [],
- "outputs": [
- {
- "name": "NOISE",
- "type": "NOISE",
- "links": [
- 37
- ],
- "shape": 3
- }
- ],
- "properties": {
- "Node name for S&R": "RandomNoise"
- },
- "widgets_values": [
- 5770521,
- "fixed"
- ],
- "color": "#2a363b",
- "bgcolor": "#3f5159"
- },
{
"id": 73,
"type": "VAEDecodeTiled",
@@ -685,7 +613,7 @@
],
"size": [
451.07391357421875,
- 592.0040893554688
+ 334
],
"flags": {},
"order": 16,
@@ -751,6 +679,80 @@
"muted": false
}
}
+ },
+ {
+ "id": 115,
+ "type": "UnetLoaderGGUFDisTorchMultiGPU",
+ "pos": [
+ -810.4765014648438,
+ 219.3965301513672
+ ],
+ "size": [
+ 342.1245422363281,
+ 154
+ ],
+ "flags": {},
+ "order": 6,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "MODEL",
+ "type": "MODEL",
+ "links": [
+ 276,
+ 277
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "UnetLoaderGGUFDisTorchMultiGPU"
+ },
+ "widgets_values": [
+ "hunyuan-video-t2v-720p-Q4_K_M.gguf",
+ "cuda:0",
+ 4,
+ false,
+ ""
+ ],
+ "color": "#233",
+ "bgcolor": "#355"
+ },
+ {
+ "id": 25,
+ "type": "RandomNoise",
+ "pos": [
+ 368.4217834472656,
+ 72.61695861816406
+ ],
+ "size": [
+ 250.37998962402344,
+ 82
+ ],
+ "flags": {},
+ "order": 7,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "NOISE",
+ "type": "NOISE",
+ "links": [
+ 37
+ ],
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "RandomNoise"
+ },
+ "widgets_values": [
+ 5770521,
+ "fixed"
+ ],
+ "color": "#2a363b",
+ "bgcolor": "#3f5159"
}
],
"links": [
@@ -901,16 +903,18 @@
"config": {},
"extra": {
"ds": {
- "scale": 0.7247295000001047,
- "offset": [
- 1743.9442159363227,
- 215.31117435648653
- ]
+ "scale": 1,
+ "offset": {
+ "0": 1075.0079345703125,
+ "1": 156.88380432128906
+ }
},
"groupNodes": {},
"ue_links": [],
"VHS_latentpreview": false,
- "VHS_latentpreviewrate": 0
+ "VHS_latentpreviewrate": 0,
+ "VHS_MetadataImage": true,
+ "VHS_KeepIntermediate": true
},
"version": 0.4
}
\ No newline at end of file
diff --git a/examples/hunyuanvideowrapper_diffsynth.json b/examples/hunyuanvideowrapper_diffsynth.json
deleted file mode 100644
index d2e531c..0000000
--- a/examples/hunyuanvideowrapper_diffsynth.json
+++ /dev/null
@@ -1,575 +0,0 @@
-{
- "last_node_id": 57,
- "last_link_id": 75,
- "nodes": [
- {
- "id": 34,
- "type": "VHS_VideoCombine",
- "pos": [
- 847.0758666992188,
- -415.1882629394531
- ],
- "size": [
- 512.8807373046875,
- 1128.39453125
- ],
- "flags": {},
- "order": 9,
- "mode": 0,
- "inputs": [
- {
- "name": "images",
- "type": "IMAGE",
- "link": 69
- },
- {
- "name": "audio",
- "type": "AUDIO",
- "link": null,
- "shape": 7
- },
- {
- "name": "meta_batch",
- "type": "VHS_BatchManager",
- "link": null,
- "shape": 7
- },
- {
- "name": "vae",
- "type": "VAE",
- "link": null,
- "shape": 7
- }
- ],
- "outputs": [
- {
- "name": "Filenames",
- "type": "VHS_FILENAMES",
- "links": null
- }
- ],
- "properties": {
- "Node name for S&R": "VHS_VideoCombine"
- },
- "widgets_values": {
- "frame_rate": 24,
- "loop_count": 0,
- "filename_prefix": "HunyuanVideo",
- "format": "video/h264-mp4",
- "pix_fmt": "yuv420p",
- "crf": 19,
- "save_metadata": true,
- "trim_to_audio": false,
- "pingpong": false,
- "save_output": true,
- "videopreview": {
- "hidden": false,
- "paused": false,
- "params": {
- "filename": "HunyuanVideo_00182.mp4",
- "subfolder": "",
- "type": "output",
- "format": "video/h264-mp4",
- "frame_rate": 24,
- "workflow": "HunyuanVideo_00182.png",
- "fullpath": "/home/johnj/ComfyUI/output/HunyuanVideo_00182.mp4"
- },
- "muted": false
- }
- }
- },
- {
- "id": 45,
- "type": "VAEDecodeTiled",
- "pos": [
- 604.5225830078125,
- -401.70220947265625
- ],
- "size": [
- 210,
- 150
- ],
- "flags": {},
- "order": 8,
- "mode": 0,
- "inputs": [
- {
- "name": "samples",
- "type": "LATENT",
- "link": 70
- },
- {
- "name": "vae",
- "type": "VAE",
- "link": 56
- }
- ],
- "outputs": [
- {
- "name": "IMAGE",
- "type": "IMAGE",
- "links": [
- 69
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "VAEDecodeTiled"
- },
- "widgets_values": [
- 256,
- 64,
- 64,
- 8
- ]
- },
- {
- "id": 44,
- "type": "VAELoaderMultiGPU",
- "pos": [
- 208.21218872070312,
- -586.37841796875
- ],
- "size": [
- 353.3572692871094,
- 84.02234649658203
- ],
- "flags": {},
- "order": 0,
- "mode": 0,
- "inputs": [],
- "outputs": [
- {
- "name": "VAE",
- "type": "VAE",
- "links": [
- 56
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "VAELoaderMultiGPU"
- },
- "widgets_values": [
- "hunyuan_video_vae_bf16.safetensors",
- "cuda:1"
- ],
- "color": "#233",
- "bgcolor": "#355"
- },
- {
- "id": 53,
- "type": "HyVideoTextImageEncode",
- "pos": [
- -163.92579650878906,
- -51.38969421386719
- ],
- "size": [
- 367.4625244140625,
- 528.5474853515625
- ],
- "flags": {},
- "order": 6,
- "mode": 0,
- "inputs": [
- {
- "name": "text_encoders",
- "type": "HYVIDTEXTENCODER",
- "link": 74
- },
- {
- "name": "custom_prompt_template",
- "type": "PROMPT_TEMPLATE",
- "link": null,
- "shape": 7
- },
- {
- "name": "clip_l",
- "type": "CLIP",
- "link": null,
- "shape": 7
- },
- {
- "name": "image1",
- "type": "IMAGE",
- "link": 73,
- "shape": 7
- },
- {
- "name": "image2",
- "type": "IMAGE",
- "link": null,
- "shape": 7
- },
- {
- "name": "hyvid_cfg",
- "type": "HYVID_CFG",
- "link": null,
- "shape": 7
- }
- ],
- "outputs": [
- {
- "name": "hyvid_embeds",
- "type": "HYVIDEMBEDS",
- "links": [
- 75
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "HyVideoTextImageEncode"
- },
- "widgets_values": [
- "The animal shown in appears within its own natural setting, moving calmly or resting in place as a soft light casts delicate shadows across its form. Over the course of five seconds, it makes subtle shifts in posture or position, revealing small details of its features, such as the texture of its skin or fur, and the quiet rhythm of its breathing.",
- "::3",
- true,
- "video",
- ""
- ]
- },
- {
- "id": 54,
- "type": "LoadImage",
- "pos": [
- -526.0797119140625,
- 233.78311157226562
- ],
- "size": [
- 315,
- 314
- ],
- "flags": {},
- "order": 1,
- "mode": 0,
- "inputs": [],
- "outputs": [
- {
- "name": "IMAGE",
- "type": "IMAGE",
- "links": [
- 73
- ],
- "slot_index": 0
- },
- {
- "name": "MASK",
- "type": "MASK",
- "links": null
- }
- ],
- "properties": {
- "Node name for S&R": "LoadImage"
- },
- "widgets_values": [
- "pasted/image (165).png",
- "image"
- ]
- },
- {
- "id": 49,
- "type": "DownloadAndLoadHyVideoTextEncoderMultiGPU",
- "pos": [
- -591.7539672851562,
- -37.14900588989258
- ],
- "size": [
- 380.8912353515625,
- 202
- ],
- "flags": {},
- "order": 2,
- "mode": 0,
- "inputs": [],
- "outputs": [
- {
- "name": "hyvid_text_encoder",
- "type": "HYVIDTEXTENCODER",
- "links": [
- 74
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "DownloadAndLoadHyVideoTextEncoderMultiGPU"
- },
- "widgets_values": [
- "xtuner/llava-llama-3-8b-v1_1-transformers",
- "openai/clip-vit-large-patch14",
- "bf16",
- false,
- 2,
- "disabled",
- "cuda:0"
- ],
- "color": "#233",
- "bgcolor": "#355"
- },
- {
- "id": 3,
- "type": "HyVideoSampler",
- "pos": [
- 255.96482849121094,
- -403.58502197265625
- ],
- "size": [
- 315,
- 630
- ],
- "flags": {},
- "order": 7,
- "mode": 0,
- "inputs": [
- {
- "name": "model",
- "type": "HYVIDEOMODEL",
- "link": 71
- },
- {
- "name": "hyvid_embeds",
- "type": "HYVIDEMBEDS",
- "link": 75
- },
- {
- "name": "samples",
- "type": "LATENT",
- "link": null,
- "shape": 7
- },
- {
- "name": "stg_args",
- "type": "STGARGS",
- "link": null,
- "shape": 7
- },
- {
- "name": "context_options",
- "type": "HYVIDCONTEXT",
- "link": null,
- "shape": 7
- },
- {
- "name": "feta_args",
- "type": "FETAARGS",
- "link": null,
- "shape": 7
- },
- {
- "name": "teacache_args",
- "type": "TEACACHEARGS",
- "link": null,
- "shape": 7
- }
- ],
- "outputs": [
- {
- "name": "samples",
- "type": "LATENT",
- "links": [
- 70
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "HyVideoSampler"
- },
- "widgets_values": [
- 768,
- 1216,
- 101,
- 30,
- 7.5,
- 7.5,
- 5770521,
- "fixed",
- true,
- 1,
- "FlowMatchDiscreteScheduler"
- ]
- },
- {
- "id": 52,
- "type": "HyVideoModelLoaderDiffSynthMultiGPU",
- "pos": [
- -217.43194580078125,
- -401.6243896484375
- ],
- "size": [
- 441,
- 218
- ],
- "flags": {},
- "order": 3,
- "mode": 0,
- "inputs": [
- {
- "name": "compile_args",
- "type": "COMPILEARGS",
- "link": null,
- "shape": 7
- },
- {
- "name": "block_swap_args",
- "type": "BLOCKSWAPARGS",
- "link": null,
- "shape": 7
- },
- {
- "name": "lora",
- "type": "HYVIDLORA",
- "link": null,
- "shape": 7
- }
- ],
- "outputs": [
- {
- "name": "model",
- "type": "HYVIDEOMODEL",
- "links": [
- 71
- ],
- "slot_index": 0
- }
- ],
- "properties": {
- "Node name for S&R": "HyVideoModelLoaderDiffSynthMultiGPU"
- },
- "widgets_values": [
- "hunyuan_video_FastVideo_720_fp8_e4m3fn.safetensors",
- "bf16",
- "fp8_e4m3fn_fast",
- "sageattn_varlen",
- "cuda:0",
- "cuda:1"
- ],
- "color": "#233",
- "bgcolor": "#355"
- },
- {
- "id": 57,
- "type": "Note",
- "pos": [
- 256.481689453125,
- 293.84710693359375
- ],
- "size": [
- 389.5359191894531,
- 349.2815856933594
- ],
- "flags": {},
- "order": 4,
- "mode": 0,
- "inputs": [],
- "outputs": [],
- "title": "Explanation of Memory Constraints and OOM Behavior",
- "properties": {},
- "widgets_values": [
- "The settings in this workflow deliberately push memory usage beyond what a single 24GB RTX 3090 can handle. As a result, UNet blocks must be offloaded to an offload_device, which is assumed to be a second 24GB RTX 3090. The chosen resolution and number of frames illustrate that one-megapixel image size videos over four seconds long can be generated—even though it exceeds the primary GPU's native memory capacity using the \"just-in-time\" DiffSynth block-swapping approach. The DiffSynth JiT algorithm is straightforward, but not optimized for speed.\n\n**Expected OOM Behavior**\n\n* One Initial \"Out of Memory\"\nSeeing a single OOM error at the start is normal for this workflow. It happens because kijai's HunyuanVideo Sampler node initially attempts a full load on \"device\", even if it will surpass available VRAM. A second attempt using the same generation parameters will correctly trigger the offload process to \"offload_device\".\n\n* Repeated OOM Errors \nIf you keep getting OOM errors with the same settings (beyond the first one), then the requirements of your generation parameters still exceed what your system—even with offloading—can manage. You may need to lower resolution, shorten video length, or upgrade hardware resources."
- ],
- "color": "#233",
- "bgcolor": "#355"
- },
- {
- "id": 51,
- "type": "Note",
- "pos": [
- -793.3005981445312,
- -466.9315490722656
- ],
- "size": [
- 564.3460693359375,
- 355.50164794921875
- ],
- "flags": {},
- "order": 5,
- "mode": 0,
- "inputs": [],
- "outputs": [],
- "title": "****FIRST ATTEMPT LOADS ONLY ON PRIMARY DEVICE, POSSIBLE OOM****",
- "properties": {},
- "widgets_values": [
- "The MultiGPU implementation for HunyuanVideo now offers two approaches:\n1. The original workflow (examples/hunyuanvideowrapper_native_vae.json)\n2. A new experimental DiffSynth-enabled workflow that enables more efficient multi-GPU usage (examples/hunyuanvideowrapper_DiffSynth.json)\n\nNew DiffSynth-Based Workflow (Experimental - THIS WORKFLOW):\n* Uses the \"HyVideoModelLoaderDiffSynthMultiGPU\" node which implements DiffSynth's memory management approach with TWO device selections\n* Adds a second device selector \"offload_device\" specifically for model offloading\n* Automatically enables efficient block swapping between GPUs via kijai's adaptation of the DiffSynth methodology\n* Provides better memory utilization by keeping actively computed blocks in VRAM\n* Assumes a 2-device solution and sets \"force_offload\" to \"true\" to avoid VAE loader OOM issues. A third 3090, for instance could be used and thus the VAE would stay in memory as well\n\nKnown Behaviors:\n* Initial OOM errors are expected and consistent with the underlying implementation, occurring in the attention mechanism of the first double block\n* Second attempts typically succeed regardless of offload device selection (CPU or GPU)\n* When running, the secondary device shows active utilization, confirming proper block swapping\n\n***** Will require a second attempt if first generation fails with OOM****\n\nNOTE: The original workflow remains the recommended stable approach. The DiffSynth-based version is provided as an experimental alternative for users who want to explore more aggressive memory optimization strategies to extend either resolution or duration options at the expense of speed."
- ],
- "color": "#233",
- "bgcolor": "#355"
- }
- ],
- "links": [
- [
- 56,
- 44,
- 0,
- 45,
- 1,
- "VAE"
- ],
- [
- 69,
- 45,
- 0,
- 34,
- 0,
- "IMAGE"
- ],
- [
- 70,
- 3,
- 0,
- 45,
- 0,
- "LATENT"
- ],
- [
- 71,
- 52,
- 0,
- 3,
- 0,
- "HYVIDEOMODEL"
- ],
- [
- 73,
- 54,
- 0,
- 53,
- 3,
- "IMAGE"
- ],
- [
- 74,
- 49,
- 0,
- 53,
- 0,
- "HYVIDTEXTENCODER"
- ],
- [
- 75,
- 53,
- 0,
- 3,
- 1,
- "HYVIDEMBEDS"
- ]
- ],
- "groups": [],
- "config": {},
- "extra": {
- "ds": {
- "scale": 0.797202450000112,
- "offset": [
- 1219.7255813472686,
- 777.2824223551936
- ]
- },
- "ue_links": [],
- "VHS_latentpreview": false,
- "VHS_latentpreviewrate": 0
- },
- "version": 0.4
-}
\ No newline at end of file
diff --git a/examples/ltxvideo_gguf_distorch_lowvram_highdram.json b/examples/ltxvideo_gguf_distorch_lowvram_highdram.json
new file mode 100755
index 0000000..ad2699d
--- /dev/null
+++ b/examples/ltxvideo_gguf_distorch_lowvram_highdram.json
@@ -0,0 +1,2762 @@
+{
+ "last_node_id": 313,
+ "last_link_id": 779,
+ "nodes": [
+ {
+ "id": 271,
+ "type": "LTXAttnOverride",
+ "pos": [
+ 2304.862060546875,
+ -951.1757202148438
+ ],
+ "size": [
+ 210,
+ 76
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 0,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "ATTN_OVERRIDE",
+ "type": "ATTN_OVERRIDE",
+ "links": [
+ 716
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LTXAttnOverride"
+ },
+ "widgets_values": [
+ "14"
+ ]
+ },
+ {
+ "id": 276,
+ "type": "EmptyLTXVLatentVideo",
+ "pos": [
+ 2054.917236328125,
+ -266.39617919921875
+ ],
+ "size": [
+ 210,
+ 130
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 10,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "width",
+ "type": "INT",
+ "link": 727,
+ "widget": {
+ "name": "width"
+ }
+ },
+ {
+ "name": "height",
+ "type": "INT",
+ "link": 728,
+ "widget": {
+ "name": "height"
+ }
+ }
+ ],
+ "outputs": [
+ {
+ "name": "LATENT",
+ "type": "LATENT",
+ "links": [
+ 730,
+ 739
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "EmptyLTXVLatentVideo",
+ "enableTabs": false,
+ "tabWidth": 65,
+ "tabXOffset": 10,
+ "hasSecondTab": false,
+ "secondTabText": "Send Back",
+ "secondTabOffset": 80,
+ "secondTabWidth": 65
+ },
+ "widgets_values": [
+ 512,
+ 768,
+ 129,
+ 1
+ ]
+ },
+ {
+ "id": 278,
+ "type": "LTXVScheduler",
+ "pos": [
+ 2308.156005859375,
+ -289.2124938964844
+ ],
+ "size": [
+ 210,
+ 154
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 13,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "latent",
+ "type": "LATENT",
+ "link": 730,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "SIGMAS",
+ "type": "SIGMAS",
+ "links": [
+ 738
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LTXVScheduler",
+ "enableTabs": false,
+ "tabWidth": 65,
+ "tabXOffset": 10,
+ "hasSecondTab": false,
+ "secondTabText": "Send Back",
+ "secondTabOffset": 80,
+ "secondTabWidth": 65
+ },
+ "widgets_values": [
+ 100,
+ 2.05,
+ 0.95,
+ true,
+ 0.1
+ ]
+ },
+ {
+ "id": 277,
+ "type": "KSamplerSelect",
+ "pos": [
+ 2291.593994140625,
+ -388.44921875
+ ],
+ "size": [
+ 210,
+ 58
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 1,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "SAMPLER",
+ "type": "SAMPLER",
+ "links": [
+ 737
+ ]
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "KSamplerSelect",
+ "enableTabs": false,
+ "tabWidth": 65,
+ "tabXOffset": 10,
+ "hasSecondTab": false,
+ "secondTabText": "Send Back",
+ "secondTabOffset": 80,
+ "secondTabWidth": 65
+ },
+ "widgets_values": [
+ "euler"
+ ]
+ },
+ {
+ "id": 275,
+ "type": "LTXVConditioning",
+ "pos": [
+ 2285.292236328125,
+ -512.1409912109375
+ ],
+ "size": [
+ 210,
+ 78
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 14,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "positive",
+ "type": "CONDITIONING",
+ "link": 725
+ },
+ {
+ "name": "negative",
+ "type": "CONDITIONING",
+ "link": 726
+ }
+ ],
+ "outputs": [
+ {
+ "name": "positive",
+ "type": "CONDITIONING",
+ "links": [
+ 735
+ ],
+ "slot_index": 0
+ },
+ {
+ "name": "negative",
+ "type": "CONDITIONING",
+ "links": [
+ 736
+ ],
+ "slot_index": 1
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LTXVConditioning",
+ "enableTabs": false,
+ "tabWidth": 65,
+ "tabXOffset": 10,
+ "hasSecondTab": false,
+ "secondTabText": "Send Back",
+ "secondTabOffset": 80,
+ "secondTabWidth": 65
+ },
+ "widgets_values": [
+ 25
+ ],
+ "color": "#232",
+ "bgcolor": "#353"
+ },
+ {
+ "id": 273,
+ "type": "LTXVImgToVideo",
+ "pos": [
+ 2062.09521484375,
+ -511.68597412109375
+ ],
+ "size": [
+ 210,
+ 206
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 11,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "positive",
+ "type": "CONDITIONING",
+ "link": 717
+ },
+ {
+ "name": "negative",
+ "type": "CONDITIONING",
+ "link": 718
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": 779
+ },
+ {
+ "name": "image",
+ "type": "IMAGE",
+ "link": 720
+ },
+ {
+ "name": "width",
+ "type": "INT",
+ "link": 721,
+ "widget": {
+ "name": "width"
+ }
+ },
+ {
+ "name": "height",
+ "type": "INT",
+ "link": 722,
+ "widget": {
+ "name": "height"
+ }
+ }
+ ],
+ "outputs": [
+ {
+ "name": "positive",
+ "type": "CONDITIONING",
+ "links": [
+ 725
+ ],
+ "slot_index": 0
+ },
+ {
+ "name": "negative",
+ "type": "CONDITIONING",
+ "links": [
+ 726
+ ],
+ "slot_index": 1
+ },
+ {
+ "name": "latent",
+ "type": "LATENT",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LTXVImgToVideo"
+ },
+ "widgets_values": [
+ 512,
+ 768,
+ 129,
+ 1,
+ 0.15
+ ],
+ "color": "#232",
+ "bgcolor": "#353"
+ },
+ {
+ "id": 272,
+ "type": "LTXPerturbedAttention",
+ "pos": [
+ 2176.4609375,
+ -854.0542602539062
+ ],
+ "size": [
+ 243.60000610351562,
+ 126
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 12,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "model",
+ "type": "MODEL",
+ "link": 715
+ },
+ {
+ "name": "attn_override",
+ "type": "ATTN_OVERRIDE",
+ "link": 716,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "MODEL",
+ "type": "MODEL",
+ "links": [
+ 734
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LTXPerturbedAttention"
+ },
+ "widgets_values": [
+ 1,
+ 0.25,
+ 3
+ ]
+ },
+ {
+ "id": 232,
+ "type": "LoadImage",
+ "pos": [
+ 1299.498291015625,
+ -735.7528686523438
+ ],
+ "size": [
+ 371.3655090332031,
+ 625.0361938476562
+ ],
+ "flags": {},
+ "order": 2,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 771
+ ],
+ "slot_index": 0,
+ "shape": 3
+ },
+ {
+ "name": "MASK",
+ "type": "MASK",
+ "links": null,
+ "shape": 3
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "LoadImage"
+ },
+ "widgets_values": [
+ "ComfyUI_08535_.png",
+ "image"
+ ],
+ "color": "#ff9414",
+ "bgcolor": "#ff8000"
+ },
+ {
+ "id": 270,
+ "type": "ModifyLTXModel",
+ "pos": [
+ 2094.41845703125,
+ -941.9146118164062
+ ],
+ "size": [
+ 210,
+ 26
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 9,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "model",
+ "type": "MODEL",
+ "link": 772
+ }
+ ],
+ "outputs": [
+ {
+ "name": "MODEL",
+ "type": "MODEL",
+ "links": [
+ 715
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "ModifyLTXModel"
+ },
+ "widgets_values": []
+ },
+ {
+ "id": 312,
+ "type": "CLIPLoaderGGUFMultiGPU",
+ "pos": [
+ 1710.6820068359375,
+ -611.449462890625
+ ],
+ "size": [
+ 328.8729553222656,
+ 123.96922302246094
+ ],
+ "flags": {},
+ "order": 3,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "CLIP",
+ "type": "CLIP",
+ "links": [
+ 776,
+ 777
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "CLIPLoaderGGUFMultiGPU"
+ },
+ "widgets_values": [
+ "t5-v1_1-xxl-encoder-Q8_0.gguf",
+ "ltxv",
+ "cpu"
+ ],
+ "color": "#233",
+ "bgcolor": "#355"
+ },
+ {
+ "id": 283,
+ "type": "SamplerCustom",
+ "pos": [
+ 2520.345703125,
+ -559.6461181640625
+ ],
+ "size": [
+ 236.8000030517578,
+ 443.8398132324219
+ ],
+ "flags": {},
+ "order": 15,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "model",
+ "type": "MODEL",
+ "link": 734
+ },
+ {
+ "name": "positive",
+ "type": "CONDITIONING",
+ "link": 735
+ },
+ {
+ "name": "negative",
+ "type": "CONDITIONING",
+ "link": 736
+ },
+ {
+ "name": "sampler",
+ "type": "SAMPLER",
+ "link": 737
+ },
+ {
+ "name": "sigmas",
+ "type": "SIGMAS",
+ "link": 738
+ },
+ {
+ "name": "latent_image",
+ "type": "LATENT",
+ "link": 739
+ }
+ ],
+ "outputs": [
+ {
+ "name": "output",
+ "type": "LATENT",
+ "links": [
+ 731
+ ],
+ "slot_index": 0
+ },
+ {
+ "name": "denoised_output",
+ "type": "LATENT",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "SamplerCustom",
+ "enableTabs": false,
+ "tabWidth": 65,
+ "tabXOffset": 10,
+ "hasSecondTab": false,
+ "secondTabText": "Send Back",
+ "secondTabOffset": 80,
+ "secondTabWidth": 65
+ },
+ "widgets_values": [
+ true,
+ 5770521,
+ "fixed",
+ 3
+ ]
+ },
+ {
+ "id": 280,
+ "type": "VHS_VideoCombine",
+ "pos": [
+ 2537.47509765625,
+ -953.67626953125
+ ],
+ "size": [
+ 281.3041687011719,
+ 334
+ ],
+ "flags": {},
+ "order": 17,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "images",
+ "type": "IMAGE",
+ "link": 733
+ },
+ {
+ "name": "audio",
+ "type": "AUDIO",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "meta_batch",
+ "type": "VHS_BatchManager",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": null,
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "Filenames",
+ "type": "VHS_FILENAMES",
+ "links": null
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VHS_VideoCombine",
+ "enableTabs": false,
+ "tabWidth": 65,
+ "tabXOffset": 10,
+ "hasSecondTab": false,
+ "secondTabText": "Send Back",
+ "secondTabOffset": 80,
+ "secondTabWidth": 65
+ },
+ "widgets_values": {
+ "frame_rate": 24,
+ "loop_count": 0,
+ "filename_prefix": "LTXVideo",
+ "format": "video/h264-mp4",
+ "pix_fmt": "yuv420p",
+ "crf": 19,
+ "save_metadata": true,
+ "trim_to_audio": false,
+ "pingpong": false,
+ "save_output": true,
+ "videopreview": {
+ "hidden": false,
+ "paused": false,
+ "params": {
+ "filename": "LTXVideo_00383.mp4",
+ "subfolder": "",
+ "type": "output",
+ "format": "video/h264-mp4",
+ "frame_rate": 24,
+ "workflow": "LTXVideo_00383.png",
+ "fullpath": "/home/johnj/ComfyUI/output/LTXVideo_00383.mp4"
+ },
+ "muted": false
+ }
+ }
+ },
+ {
+ "id": 279,
+ "type": "VAEDecode",
+ "pos": [
+ 2414.28564453125,
+ -635.2009887695312
+ ],
+ "size": [
+ 140,
+ 46
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 16,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "samples",
+ "type": "LATENT",
+ "link": 731
+ },
+ {
+ "name": "vae",
+ "type": "VAE",
+ "link": 778
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 733
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VAEDecode",
+ "enableTabs": false,
+ "tabWidth": 65,
+ "tabXOffset": 10,
+ "hasSecondTab": false,
+ "secondTabText": "Send Back",
+ "secondTabOffset": 80,
+ "secondTabWidth": 65
+ },
+ "widgets_values": []
+ },
+ {
+ "id": 269,
+ "type": "CLIPTextEncode",
+ "pos": [
+ 2129.7138671875,
+ -660.4461669921875
+ ],
+ "size": [
+ 285.6000061035156,
+ 76
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 8,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "clip",
+ "type": "CLIP",
+ "link": 777
+ }
+ ],
+ "outputs": [
+ {
+ "name": "CONDITIONING",
+ "type": "CONDITIONING",
+ "links": [
+ 718
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "CLIP Text Encode (Negative Prompt)",
+ "properties": {
+ "Node name for S&R": "CLIPTextEncode",
+ "enableTabs": false,
+ "tabWidth": 65,
+ "tabXOffset": 10,
+ "hasSecondTab": false,
+ "secondTabText": "Send Back",
+ "secondTabOffset": 80,
+ "secondTabWidth": 65
+ },
+ "widgets_values": [
+ "low quality, worst quality, deformed, distorted, disfigured, motion smear, motion artifacts, fused fingers, bad anatomy, weird hand, ugly"
+ ],
+ "color": "#322",
+ "bgcolor": "#533"
+ },
+ {
+ "id": 268,
+ "type": "CLIPTextEncode",
+ "pos": [
+ 1724.329833984375,
+ -756.010986328125
+ ],
+ "size": [
+ 358.89739990234375,
+ 117.5052490234375
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 7,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "clip",
+ "type": "CLIP",
+ "link": 776
+ }
+ ],
+ "outputs": [
+ {
+ "name": "CONDITIONING",
+ "type": "CONDITIONING",
+ "links": [
+ 717
+ ],
+ "slot_index": 0
+ }
+ ],
+ "title": "LTXV Pos",
+ "properties": {
+ "Node name for S&R": "CLIPTextEncode",
+ "enableTabs": false,
+ "tabWidth": 65,
+ "tabXOffset": 10,
+ "hasSecondTab": false,
+ "secondTabText": "Send Back",
+ "secondTabOffset": 80,
+ "secondTabWidth": 65
+ },
+ "widgets_values": [
+ "This describes the first frame of a video that needs to subtly animated for 5 seconds: The image is a black and white photograph of a waterfall. The waterfall is cascading down a rocky cliff, with the water flowing over the rocks and creating a misty effect. The rocks are large and jagged, and the water is flowing over them. The cliff is covered in trees and shrubs, and there is a hill in the background. The sky is overcast and the overall mood of the image is peaceful and serene."
+ ],
+ "color": "#232",
+ "bgcolor": "#353"
+ },
+ {
+ "id": 308,
+ "type": "UnetLoaderGGUFDisTorchMultiGPU",
+ "pos": [
+ 1738.21630859375,
+ -938.6461791992188
+ ],
+ "size": [
+ 339.9610290527344,
+ 154
+ ],
+ "flags": {},
+ "order": 4,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "MODEL",
+ "type": "MODEL",
+ "links": [
+ 772
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "UnetLoaderGGUFDisTorchMultiGPU"
+ },
+ "widgets_values": [
+ "ltx-video-2b-v0.9.1-F16.gguf",
+ "cuda:0",
+ 4,
+ false,
+ ""
+ ],
+ "color": "#233",
+ "bgcolor": "#355"
+ },
+ {
+ "id": 274,
+ "type": "ImageResizeKJ",
+ "pos": [
+ 1734.0921630859375,
+ -350.01019287109375
+ ],
+ "size": [
+ 210,
+ 238
+ ],
+ "flags": {
+ "collapsed": false
+ },
+ "order": 6,
+ "mode": 0,
+ "inputs": [
+ {
+ "name": "image",
+ "type": "IMAGE",
+ "link": 771
+ },
+ {
+ "name": "get_image_size",
+ "type": "IMAGE",
+ "link": null,
+ "shape": 7
+ },
+ {
+ "name": "width_input",
+ "type": "INT",
+ "link": null,
+ "widget": {
+ "name": "width_input"
+ },
+ "shape": 7
+ },
+ {
+ "name": "height_input",
+ "type": "INT",
+ "link": null,
+ "widget": {
+ "name": "height_input"
+ },
+ "shape": 7
+ }
+ ],
+ "outputs": [
+ {
+ "name": "IMAGE",
+ "type": "IMAGE",
+ "links": [
+ 720
+ ],
+ "slot_index": 0
+ },
+ {
+ "name": "width",
+ "type": "INT",
+ "links": [
+ 721,
+ 727
+ ],
+ "slot_index": 1
+ },
+ {
+ "name": "height",
+ "type": "INT",
+ "links": [
+ 722,
+ 728
+ ],
+ "slot_index": 2
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "ImageResizeKJ"
+ },
+ "widgets_values": [
+ 768,
+ 768,
+ "nearest-exact",
+ true,
+ 16,
+ 0,
+ 0,
+ "center"
+ ]
+ },
+ {
+ "id": 313,
+ "type": "VAELoaderMultiGPU",
+ "pos": [
+ 1725.0933837890625,
+ -463.51104736328125
+ ],
+ "size": [
+ 315,
+ 82
+ ],
+ "flags": {},
+ "order": 5,
+ "mode": 0,
+ "inputs": [],
+ "outputs": [
+ {
+ "name": "VAE",
+ "type": "VAE",
+ "links": [
+ 778,
+ 779
+ ],
+ "slot_index": 0
+ }
+ ],
+ "properties": {
+ "Node name for S&R": "VAELoaderMultiGPU"
+ },
+ "widgets_values": [
+ "ltxv-0.9.1-vae.safetensors",
+ "cuda:0"
+ ],
+ "color": "#233",
+ "bgcolor": "#355"
+ }
+ ],
+ "links": [
+ [
+ 439,
+ 132,
+ 0,
+ 65,
+ 1,
+ "INT"
+ ],
+ [
+ 440,
+ 111,
+ 0,
+ 8,
+ 1,
+ "VAE"
+ ],
+ [
+ 441,
+ 111,
+ 0,
+ 141,
+ 1,
+ "VAE"
+ ],
+ [
+ 442,
+ 128,
+ 0,
+ 149,
+ 0,
+ "NOISE"
+ ],
+ [
+ 443,
+ 130,
+ 0,
+ 149,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 444,
+ 27,
+ 0,
+ 149,
+ 4,
+ "LATENT"
+ ],
+ [
+ 445,
+ 128,
+ 0,
+ 127,
+ 0,
+ "NOISE"
+ ],
+ [
+ 446,
+ 130,
+ 0,
+ 127,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 447,
+ 27,
+ 0,
+ 127,
+ 4,
+ "LATENT"
+ ],
+ [
+ 448,
+ 128,
+ 0,
+ 61,
+ 0,
+ "NOISE"
+ ],
+ [
+ 449,
+ 130,
+ 0,
+ 61,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 450,
+ 27,
+ 0,
+ 61,
+ 4,
+ "LATENT"
+ ],
+ [
+ 451,
+ 128,
+ 0,
+ 143,
+ 0,
+ "NOISE"
+ ],
+ [
+ 452,
+ 130,
+ 0,
+ 143,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 453,
+ 27,
+ 0,
+ 143,
+ 4,
+ "LATENT"
+ ],
+ [
+ 454,
+ 132,
+ 0,
+ 131,
+ 1,
+ "INT"
+ ],
+ [
+ 455,
+ 111,
+ 0,
+ 123,
+ 1,
+ "VAE"
+ ],
+ [
+ 456,
+ 132,
+ 0,
+ 145,
+ 1,
+ "INT"
+ ],
+ [
+ 457,
+ 198,
+ 0,
+ 151,
+ 0,
+ "MODEL"
+ ],
+ [
+ 458,
+ 132,
+ 0,
+ 151,
+ 1,
+ "INT"
+ ],
+ [
+ 459,
+ 198,
+ 0,
+ 150,
+ 0,
+ "MODEL"
+ ],
+ [
+ 460,
+ 113,
+ 0,
+ 219,
+ 0,
+ "CLIP"
+ ],
+ [
+ 461,
+ 113,
+ 0,
+ 214,
+ 0,
+ "CLIP"
+ ],
+ [
+ 462,
+ 198,
+ 0,
+ 146,
+ 0,
+ "MODEL"
+ ],
+ [
+ 463,
+ 198,
+ 0,
+ 134,
+ 0,
+ "MODEL"
+ ],
+ [
+ 464,
+ 113,
+ 0,
+ 223,
+ 0,
+ "CLIP"
+ ],
+ [
+ 465,
+ 111,
+ 0,
+ 147,
+ 1,
+ "VAE"
+ ],
+ [
+ 466,
+ 198,
+ 0,
+ 122,
+ 0,
+ "MODEL"
+ ],
+ [
+ 467,
+ 113,
+ 0,
+ 6,
+ 0,
+ "CLIP"
+ ],
+ [
+ 491,
+ 132,
+ 0,
+ 65,
+ 1,
+ "INT"
+ ],
+ [
+ 492,
+ 111,
+ 0,
+ 8,
+ 1,
+ "VAE"
+ ],
+ [
+ 493,
+ 111,
+ 0,
+ 141,
+ 1,
+ "VAE"
+ ],
+ [
+ 494,
+ 128,
+ 0,
+ 127,
+ 0,
+ "NOISE"
+ ],
+ [
+ 495,
+ 130,
+ 0,
+ 127,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 496,
+ 27,
+ 0,
+ 127,
+ 4,
+ "LATENT"
+ ],
+ [
+ 497,
+ 128,
+ 0,
+ 61,
+ 0,
+ "NOISE"
+ ],
+ [
+ 498,
+ 130,
+ 0,
+ 61,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 499,
+ 27,
+ 0,
+ 61,
+ 4,
+ "LATENT"
+ ],
+ [
+ 500,
+ 132,
+ 0,
+ 131,
+ 1,
+ "INT"
+ ],
+ [
+ 501,
+ 132,
+ 0,
+ 145,
+ 1,
+ "INT"
+ ],
+ [
+ 502,
+ 113,
+ 0,
+ 219,
+ 0,
+ "CLIP"
+ ],
+ [
+ 503,
+ 113,
+ 0,
+ 214,
+ 0,
+ "CLIP"
+ ],
+ [
+ 504,
+ 198,
+ 0,
+ 146,
+ 0,
+ "MODEL"
+ ],
+ [
+ 505,
+ 198,
+ 0,
+ 134,
+ 0,
+ "MODEL"
+ ],
+ [
+ 506,
+ 113,
+ 0,
+ 223,
+ 0,
+ "CLIP"
+ ],
+ [
+ 507,
+ 111,
+ 0,
+ 147,
+ 1,
+ "VAE"
+ ],
+ [
+ 508,
+ 198,
+ 0,
+ 122,
+ 0,
+ "MODEL"
+ ],
+ [
+ 509,
+ 113,
+ 0,
+ 6,
+ 0,
+ "CLIP"
+ ],
+ [
+ 510,
+ 128,
+ 0,
+ 149,
+ 0,
+ "NOISE"
+ ],
+ [
+ 511,
+ 130,
+ 0,
+ 149,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 512,
+ 27,
+ 0,
+ 149,
+ 4,
+ "LATENT"
+ ],
+ [
+ 513,
+ 198,
+ 0,
+ 151,
+ 0,
+ "MODEL"
+ ],
+ [
+ 514,
+ 132,
+ 0,
+ 151,
+ 1,
+ "INT"
+ ],
+ [
+ 515,
+ 198,
+ 0,
+ 150,
+ 0,
+ "MODEL"
+ ],
+ [
+ 516,
+ 128,
+ 0,
+ 143,
+ 0,
+ "NOISE"
+ ],
+ [
+ 517,
+ 130,
+ 0,
+ 143,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 518,
+ 27,
+ 0,
+ 143,
+ 4,
+ "LATENT"
+ ],
+ [
+ 519,
+ 111,
+ 0,
+ 123,
+ 1,
+ "VAE"
+ ],
+ [
+ 523,
+ 132,
+ 0,
+ 65,
+ 1,
+ "INT"
+ ],
+ [
+ 524,
+ 111,
+ 0,
+ 8,
+ 1,
+ "VAE"
+ ],
+ [
+ 525,
+ 111,
+ 0,
+ 141,
+ 1,
+ "VAE"
+ ],
+ [
+ 526,
+ 128,
+ 0,
+ 127,
+ 0,
+ "NOISE"
+ ],
+ [
+ 527,
+ 130,
+ 0,
+ 127,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 528,
+ 27,
+ 0,
+ 127,
+ 4,
+ "LATENT"
+ ],
+ [
+ 529,
+ 128,
+ 0,
+ 61,
+ 0,
+ "NOISE"
+ ],
+ [
+ 530,
+ 130,
+ 0,
+ 61,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 531,
+ 27,
+ 0,
+ 61,
+ 4,
+ "LATENT"
+ ],
+ [
+ 532,
+ 132,
+ 0,
+ 131,
+ 1,
+ "INT"
+ ],
+ [
+ 533,
+ 132,
+ 0,
+ 145,
+ 1,
+ "INT"
+ ],
+ [
+ 534,
+ 113,
+ 0,
+ 219,
+ 0,
+ "CLIP"
+ ],
+ [
+ 535,
+ 113,
+ 0,
+ 214,
+ 0,
+ "CLIP"
+ ],
+ [
+ 536,
+ 195,
+ 0,
+ 146,
+ 0,
+ "MODEL"
+ ],
+ [
+ 537,
+ 195,
+ 0,
+ 134,
+ 0,
+ "MODEL"
+ ],
+ [
+ 538,
+ 113,
+ 0,
+ 223,
+ 0,
+ "CLIP"
+ ],
+ [
+ 539,
+ 111,
+ 0,
+ 147,
+ 1,
+ "VAE"
+ ],
+ [
+ 540,
+ 195,
+ 0,
+ 122,
+ 0,
+ "MODEL"
+ ],
+ [
+ 541,
+ 113,
+ 0,
+ 6,
+ 0,
+ "CLIP"
+ ],
+ [
+ 542,
+ 128,
+ 0,
+ 149,
+ 0,
+ "NOISE"
+ ],
+ [
+ 543,
+ 130,
+ 0,
+ 149,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 544,
+ 27,
+ 0,
+ 149,
+ 4,
+ "LATENT"
+ ],
+ [
+ 545,
+ 195,
+ 0,
+ 151,
+ 0,
+ "MODEL"
+ ],
+ [
+ 546,
+ 132,
+ 0,
+ 151,
+ 1,
+ "INT"
+ ],
+ [
+ 547,
+ 195,
+ 0,
+ 150,
+ 0,
+ "MODEL"
+ ],
+ [
+ 548,
+ 128,
+ 0,
+ 143,
+ 0,
+ "NOISE"
+ ],
+ [
+ 549,
+ 130,
+ 0,
+ 143,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 550,
+ 27,
+ 0,
+ 143,
+ 4,
+ "LATENT"
+ ],
+ [
+ 551,
+ 111,
+ 0,
+ 123,
+ 1,
+ "VAE"
+ ],
+ [
+ 562,
+ 132,
+ 0,
+ 65,
+ 1,
+ "INT"
+ ],
+ [
+ 563,
+ 111,
+ 0,
+ 8,
+ 1,
+ "VAE"
+ ],
+ [
+ 564,
+ 111,
+ 0,
+ 141,
+ 1,
+ "VAE"
+ ],
+ [
+ 565,
+ 128,
+ 0,
+ 127,
+ 0,
+ "NOISE"
+ ],
+ [
+ 566,
+ 130,
+ 0,
+ 127,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 567,
+ 27,
+ 0,
+ 127,
+ 4,
+ "LATENT"
+ ],
+ [
+ 568,
+ 128,
+ 0,
+ 61,
+ 0,
+ "NOISE"
+ ],
+ [
+ 569,
+ 130,
+ 0,
+ 61,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 570,
+ 27,
+ 0,
+ 61,
+ 4,
+ "LATENT"
+ ],
+ [
+ 571,
+ 132,
+ 0,
+ 131,
+ 1,
+ "INT"
+ ],
+ [
+ 572,
+ 132,
+ 0,
+ 145,
+ 1,
+ "INT"
+ ],
+ [
+ 573,
+ 113,
+ 0,
+ 219,
+ 0,
+ "CLIP"
+ ],
+ [
+ 574,
+ 113,
+ 0,
+ 214,
+ 0,
+ "CLIP"
+ ],
+ [
+ 575,
+ 195,
+ 0,
+ 134,
+ 0,
+ "MODEL"
+ ],
+ [
+ 576,
+ 113,
+ 0,
+ 223,
+ 0,
+ "CLIP"
+ ],
+ [
+ 577,
+ 128,
+ 0,
+ 149,
+ 0,
+ "NOISE"
+ ],
+ [
+ 578,
+ 130,
+ 0,
+ 149,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 579,
+ 27,
+ 0,
+ 149,
+ 4,
+ "LATENT"
+ ],
+ [
+ 580,
+ 195,
+ 0,
+ 151,
+ 0,
+ "MODEL"
+ ],
+ [
+ 581,
+ 132,
+ 0,
+ 151,
+ 1,
+ "INT"
+ ],
+ [
+ 582,
+ 195,
+ 0,
+ 150,
+ 0,
+ "MODEL"
+ ],
+ [
+ 583,
+ 128,
+ 0,
+ 143,
+ 0,
+ "NOISE"
+ ],
+ [
+ 584,
+ 130,
+ 0,
+ 143,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 585,
+ 27,
+ 0,
+ 143,
+ 4,
+ "LATENT"
+ ],
+ [
+ 586,
+ 111,
+ 0,
+ 123,
+ 1,
+ "VAE"
+ ],
+ [
+ 587,
+ 113,
+ 0,
+ 6,
+ 0,
+ "CLIP"
+ ],
+ [
+ 588,
+ 195,
+ 0,
+ 146,
+ 0,
+ "MODEL"
+ ],
+ [
+ 589,
+ 195,
+ 0,
+ 122,
+ 0,
+ "MODEL"
+ ],
+ [
+ 590,
+ 111,
+ 0,
+ 147,
+ 1,
+ "VAE"
+ ],
+ [
+ 605,
+ 132,
+ 0,
+ 65,
+ 1,
+ "INT"
+ ],
+ [
+ 606,
+ 111,
+ 0,
+ 8,
+ 1,
+ "VAE"
+ ],
+ [
+ 607,
+ 111,
+ 0,
+ 141,
+ 1,
+ "VAE"
+ ],
+ [
+ 608,
+ 128,
+ 0,
+ 127,
+ 0,
+ "NOISE"
+ ],
+ [
+ 609,
+ 130,
+ 0,
+ 127,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 610,
+ 27,
+ 0,
+ 127,
+ 4,
+ "LATENT"
+ ],
+ [
+ 611,
+ 128,
+ 0,
+ 61,
+ 0,
+ "NOISE"
+ ],
+ [
+ 612,
+ 130,
+ 0,
+ 61,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 613,
+ 27,
+ 0,
+ 61,
+ 4,
+ "LATENT"
+ ],
+ [
+ 614,
+ 132,
+ 0,
+ 131,
+ 1,
+ "INT"
+ ],
+ [
+ 615,
+ 132,
+ 0,
+ 145,
+ 1,
+ "INT"
+ ],
+ [
+ 616,
+ 113,
+ 0,
+ 219,
+ 0,
+ "CLIP"
+ ],
+ [
+ 617,
+ 113,
+ 0,
+ 214,
+ 0,
+ "CLIP"
+ ],
+ [
+ 618,
+ 198,
+ 0,
+ 134,
+ 0,
+ "MODEL"
+ ],
+ [
+ 619,
+ 113,
+ 0,
+ 223,
+ 0,
+ "CLIP"
+ ],
+ [
+ 620,
+ 128,
+ 0,
+ 149,
+ 0,
+ "NOISE"
+ ],
+ [
+ 621,
+ 130,
+ 0,
+ 149,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 622,
+ 27,
+ 0,
+ 149,
+ 4,
+ "LATENT"
+ ],
+ [
+ 623,
+ 198,
+ 0,
+ 151,
+ 0,
+ "MODEL"
+ ],
+ [
+ 624,
+ 132,
+ 0,
+ 151,
+ 1,
+ "INT"
+ ],
+ [
+ 625,
+ 198,
+ 0,
+ 150,
+ 0,
+ "MODEL"
+ ],
+ [
+ 626,
+ 128,
+ 0,
+ 143,
+ 0,
+ "NOISE"
+ ],
+ [
+ 627,
+ 130,
+ 0,
+ 143,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 628,
+ 27,
+ 0,
+ 143,
+ 4,
+ "LATENT"
+ ],
+ [
+ 629,
+ 111,
+ 0,
+ 123,
+ 1,
+ "VAE"
+ ],
+ [
+ 630,
+ 113,
+ 0,
+ 6,
+ 0,
+ "CLIP"
+ ],
+ [
+ 631,
+ 198,
+ 0,
+ 146,
+ 0,
+ "MODEL"
+ ],
+ [
+ 632,
+ 111,
+ 0,
+ 147,
+ 1,
+ "VAE"
+ ],
+ [
+ 633,
+ 198,
+ 0,
+ 122,
+ 0,
+ "MODEL"
+ ],
+ [
+ 644,
+ 132,
+ 0,
+ 65,
+ 1,
+ "INT"
+ ],
+ [
+ 645,
+ 111,
+ 0,
+ 8,
+ 1,
+ "VAE"
+ ],
+ [
+ 646,
+ 111,
+ 0,
+ 141,
+ 1,
+ "VAE"
+ ],
+ [
+ 647,
+ 128,
+ 0,
+ 127,
+ 0,
+ "NOISE"
+ ],
+ [
+ 648,
+ 130,
+ 0,
+ 127,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 649,
+ 27,
+ 0,
+ 127,
+ 4,
+ "LATENT"
+ ],
+ [
+ 650,
+ 128,
+ 0,
+ 61,
+ 0,
+ "NOISE"
+ ],
+ [
+ 651,
+ 130,
+ 0,
+ 61,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 652,
+ 27,
+ 0,
+ 61,
+ 4,
+ "LATENT"
+ ],
+ [
+ 653,
+ 132,
+ 0,
+ 131,
+ 1,
+ "INT"
+ ],
+ [
+ 654,
+ 132,
+ 0,
+ 145,
+ 1,
+ "INT"
+ ],
+ [
+ 655,
+ 113,
+ 0,
+ 219,
+ 0,
+ "CLIP"
+ ],
+ [
+ 656,
+ 113,
+ 0,
+ 214,
+ 0,
+ "CLIP"
+ ],
+ [
+ 657,
+ 198,
+ 0,
+ 134,
+ 0,
+ "MODEL"
+ ],
+ [
+ 658,
+ 113,
+ 0,
+ 223,
+ 0,
+ "CLIP"
+ ],
+ [
+ 659,
+ 128,
+ 0,
+ 149,
+ 0,
+ "NOISE"
+ ],
+ [
+ 660,
+ 130,
+ 0,
+ 149,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 661,
+ 27,
+ 0,
+ 149,
+ 4,
+ "LATENT"
+ ],
+ [
+ 662,
+ 198,
+ 0,
+ 151,
+ 0,
+ "MODEL"
+ ],
+ [
+ 663,
+ 132,
+ 0,
+ 151,
+ 1,
+ "INT"
+ ],
+ [
+ 664,
+ 198,
+ 0,
+ 150,
+ 0,
+ "MODEL"
+ ],
+ [
+ 665,
+ 128,
+ 0,
+ 143,
+ 0,
+ "NOISE"
+ ],
+ [
+ 666,
+ 130,
+ 0,
+ 143,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 667,
+ 27,
+ 0,
+ 143,
+ 4,
+ "LATENT"
+ ],
+ [
+ 668,
+ 111,
+ 0,
+ 123,
+ 1,
+ "VAE"
+ ],
+ [
+ 669,
+ 113,
+ 0,
+ 6,
+ 0,
+ "CLIP"
+ ],
+ [
+ 670,
+ 198,
+ 0,
+ 146,
+ 0,
+ "MODEL"
+ ],
+ [
+ 671,
+ 111,
+ 0,
+ 147,
+ 1,
+ "VAE"
+ ],
+ [
+ 672,
+ 198,
+ 0,
+ 122,
+ 0,
+ "MODEL"
+ ],
+ [
+ 682,
+ 265,
+ 0,
+ 151,
+ 0,
+ "MODEL"
+ ],
+ [
+ 683,
+ 132,
+ 0,
+ 151,
+ 1,
+ "INT"
+ ],
+ [
+ 684,
+ 111,
+ 0,
+ 147,
+ 1,
+ "VAE"
+ ],
+ [
+ 685,
+ 265,
+ 0,
+ 150,
+ 0,
+ "MODEL"
+ ],
+ [
+ 686,
+ 35,
+ 0,
+ 150,
+ 1,
+ "CONDITIONING"
+ ],
+ [
+ 687,
+ 113,
+ 0,
+ 6,
+ 0,
+ "CLIP"
+ ],
+ [
+ 688,
+ 128,
+ 0,
+ 149,
+ 0,
+ "NOISE"
+ ],
+ [
+ 689,
+ 130,
+ 0,
+ 149,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 690,
+ 27,
+ 0,
+ 149,
+ 4,
+ "LATENT"
+ ],
+ [
+ 691,
+ 265,
+ 0,
+ 151,
+ 0,
+ "MODEL"
+ ],
+ [
+ 692,
+ 132,
+ 0,
+ 151,
+ 1,
+ "INT"
+ ],
+ [
+ 693,
+ 111,
+ 0,
+ 147,
+ 1,
+ "VAE"
+ ],
+ [
+ 694,
+ 265,
+ 0,
+ 150,
+ 0,
+ "MODEL"
+ ],
+ [
+ 695,
+ 35,
+ 0,
+ 150,
+ 1,
+ "CONDITIONING"
+ ],
+ [
+ 696,
+ 113,
+ 0,
+ 6,
+ 0,
+ "CLIP"
+ ],
+ [
+ 697,
+ 128,
+ 0,
+ 149,
+ 0,
+ "NOISE"
+ ],
+ [
+ 698,
+ 130,
+ 0,
+ 149,
+ 2,
+ "SAMPLER"
+ ],
+ [
+ 699,
+ 27,
+ 0,
+ 149,
+ 4,
+ "LATENT"
+ ],
+ [
+ 715,
+ 270,
+ 0,
+ 272,
+ 0,
+ "MODEL"
+ ],
+ [
+ 716,
+ 271,
+ 0,
+ 272,
+ 1,
+ "ATTN_OVERRIDE"
+ ],
+ [
+ 717,
+ 268,
+ 0,
+ 273,
+ 0,
+ "CONDITIONING"
+ ],
+ [
+ 718,
+ 269,
+ 0,
+ 273,
+ 1,
+ "CONDITIONING"
+ ],
+ [
+ 720,
+ 274,
+ 0,
+ 273,
+ 3,
+ "IMAGE"
+ ],
+ [
+ 721,
+ 274,
+ 1,
+ 273,
+ 4,
+ "INT"
+ ],
+ [
+ 722,
+ 274,
+ 2,
+ 273,
+ 5,
+ "INT"
+ ],
+ [
+ 725,
+ 273,
+ 0,
+ 275,
+ 0,
+ "CONDITIONING"
+ ],
+ [
+ 726,
+ 273,
+ 1,
+ 275,
+ 1,
+ "CONDITIONING"
+ ],
+ [
+ 727,
+ 274,
+ 1,
+ 276,
+ 0,
+ "INT"
+ ],
+ [
+ 728,
+ 274,
+ 2,
+ 276,
+ 1,
+ "INT"
+ ],
+ [
+ 730,
+ 276,
+ 0,
+ 278,
+ 0,
+ "LATENT"
+ ],
+ [
+ 731,
+ 283,
+ 0,
+ 279,
+ 0,
+ "LATENT"
+ ],
+ [
+ 733,
+ 279,
+ 0,
+ 280,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 734,
+ 272,
+ 0,
+ 283,
+ 0,
+ "MODEL"
+ ],
+ [
+ 735,
+ 275,
+ 0,
+ 283,
+ 1,
+ "CONDITIONING"
+ ],
+ [
+ 736,
+ 275,
+ 1,
+ 283,
+ 2,
+ "CONDITIONING"
+ ],
+ [
+ 737,
+ 277,
+ 0,
+ 283,
+ 3,
+ "SAMPLER"
+ ],
+ [
+ 738,
+ 278,
+ 0,
+ 283,
+ 4,
+ "SIGMAS"
+ ],
+ [
+ 739,
+ 276,
+ 0,
+ 283,
+ 5,
+ "LATENT"
+ ],
+ [
+ 771,
+ 232,
+ 0,
+ 274,
+ 0,
+ "IMAGE"
+ ],
+ [
+ 772,
+ 308,
+ 0,
+ 270,
+ 0,
+ "MODEL"
+ ],
+ [
+ 776,
+ 312,
+ 0,
+ 268,
+ 0,
+ "CLIP"
+ ],
+ [
+ 777,
+ 312,
+ 0,
+ 269,
+ 0,
+ "CLIP"
+ ],
+ [
+ 778,
+ 313,
+ 0,
+ 279,
+ 1,
+ "VAE"
+ ],
+ [
+ 779,
+ 313,
+ 0,
+ 273,
+ 2,
+ "VAE"
+ ]
+ ],
+ "groups": [
+ {
+ "id": 2,
+ "title": "img2vid",
+ "bounding": [
+ 1717.4788818359375,
+ -1023.1045532226562,
+ 1116.5592041015625,
+ 912.8241577148438
+ ],
+ "color": "#3f789e",
+ "font_size": 24,
+ "flags": {}
+ }
+ ],
+ "config": {},
+ "extra": {
+ "ds": {
+ "scale": 1.1,
+ "offset": {
+ "0": -999.0325317382812,
+ "1": 1194.420166015625
+ }
+ },
+ "ue_links": [],
+ "VHS_latentpreview": false,
+ "VHS_latentpreviewrate": 0,
+ "VHS_MetadataImage": true,
+ "VHS_KeepIntermediate": true
+ },
+ "version": 0.4
+}
\ No newline at end of file
diff --git a/nodes.py b/nodes.py
new file mode 100644
index 0000000..6c5bdeb
--- /dev/null
+++ b/nodes.py
@@ -0,0 +1,476 @@
+import os
+import torch
+import folder_paths
+from pathlib import Path
+from nodes import NODE_CLASS_MAPPINGS
+
+class UnetLoaderGGUF:
+ @classmethod
+ def INPUT_TYPES(s):
+ unet_names = [x for x in folder_paths.get_filename_list("unet_gguf")]
+ return {
+ "required": {
+ "unet_name": (unet_names,),
+ }
+ }
+
+ RETURN_TYPES = ("MODEL",)
+ FUNCTION = "load_unet"
+ CATEGORY = "bootleg"
+ TITLE = "Unet Loader (GGUF)"
+
+ def load_unet(self, unet_name, dequant_dtype=None, patch_dtype=None, patch_on_device=None):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["UnetLoaderGGUF"]()
+ return original_loader.load_unet(unet_name, dequant_dtype, patch_dtype, patch_on_device)
+
+class UnetLoaderGGUFAdvanced(UnetLoaderGGUF):
+ @classmethod
+ def INPUT_TYPES(s):
+ unet_names = [x for x in folder_paths.get_filename_list("unet_gguf")]
+ return {
+ "required": {
+ "unet_name": (unet_names,),
+ "dequant_dtype": (["default", "target", "float32", "float16", "bfloat16"], {"default": "default"}),
+ "patch_dtype": (["default", "target", "float32", "float16", "bfloat16"], {"default": "default"}),
+ "patch_on_device": ("BOOLEAN", {"default": False}),
+ }
+ }
+ TITLE = "Unet Loader (GGUF/Advanced)"
+
+
+class CLIPLoaderGGUF:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "clip_name": (s.get_filename_list(),),
+ "type": (["stable_diffusion", "stable_cascade", "sd3", "stable_audio", "mochi", "ltxv"],),
+ }
+ }
+
+ RETURN_TYPES = ("CLIP",)
+ FUNCTION = "load_clip"
+ CATEGORY = "bootleg"
+ TITLE = "CLIPLoader (GGUF)"
+
+ @classmethod
+ def get_filename_list(s):
+ files = []
+ files += folder_paths.get_filename_list("clip")
+ files += folder_paths.get_filename_list("clip_gguf")
+ return sorted(files)
+
+ def load_data(self, ckpt_paths):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["CLIPLoaderGGUF"]()
+ return original_loader.load_data(ckpt_paths)
+
+ def load_patcher(self, clip_paths, clip_type, clip_data):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["CLIPLoaderGGUF"]()
+ return original_loader.load_patcher(clip_paths, clip_type, clip_data)
+
+ def load_clip(self, clip_name, type="stable_diffusion"):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["CLIPLoaderGGUF"]()
+ return original_loader.load_clip(clip_name, type)
+
+class DualCLIPLoaderGGUF(CLIPLoaderGGUF):
+ @classmethod
+ def INPUT_TYPES(s):
+ file_options = (s.get_filename_list(), )
+ return {
+ "required": {
+ "clip_name1": file_options,
+ "clip_name2": file_options,
+ "type": (("sdxl", "sd3", "flux", "hunyuan_video"),),
+ }
+ }
+
+ TITLE = "DualCLIPLoader (GGUF)"
+
+ def load_clip(self, clip_name1, clip_name2, type):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["DualCLIPLoaderGGUF"]()
+ clip = original_loader.load_clip(clip_name1, clip_name2, type)
+ clip[0].patcher.load(force_patch_weights=True)
+ return clip
+
+
+class TripleCLIPLoaderGGUF(CLIPLoaderGGUF):
+ @classmethod
+ def INPUT_TYPES(s):
+ file_options = (s.get_filename_list(), )
+ return {
+ "required": {
+ "clip_name1": file_options,
+ "clip_name2": file_options,
+ "clip_name3": file_options,
+ }
+ }
+
+ TITLE = "TripleCLIPLoader (GGUF)"
+
+ def load_clip(self, clip_name1, clip_name2, clip_name3, type="sd3"):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["TripleCLIPLoaderGGUF"]()
+ return original_loader.load_clip(clip_name1, clip_name2, clip_name3, type)
+
+
+class LTXVLoader:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "ckpt_name": (folder_paths.get_filename_list("checkpoints"),
+ {"tooltip": "The name of the checkpoint (model) to load."}),
+ "dtype": (["bfloat16", "float32"], {"default": "bfloat16"})
+ }
+ }
+
+ RETURN_TYPES = ("MODEL", "VAE")
+ RETURN_NAMES = ("model", "vae")
+ FUNCTION = "load"
+ CATEGORY = "lightricks/LTXV"
+ TITLE = "LTXV Loader"
+ OUTPUT_NODE = False
+
+ def load(self, ckpt_name, dtype):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["LTXVLoader"]()
+ return original_loader.load(ckpt_name, dtype)
+ def _load_unet(self, load_device, offload_device, weights, num_latent_channels, dtype, config=None ):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["LTXVLoader"]()
+ return original_loader._load_unet(load_device, offload_device, weights, num_latent_channels, dtype, config=None )
+ def _load_vae(self, weights, config=None):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["LTXVLoader"]()
+ return original_loader._load_vae(weights, config=None)
+
+class Florence2ModelLoader:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {"required": {
+ "model": ([item.name for item in Path(folder_paths.models_dir, "LLM").iterdir() if item.is_dir()], {"tooltip": "models are expected to be in Comfyui/models/LLM folder"}),
+ "precision": (['fp16','bf16','fp32'],),
+ "attention": (
+ [ 'flash_attention_2', 'sdpa', 'eager'],
+ {
+ "default": 'sdpa'
+ }),
+ },
+ "optional": {
+ "lora": ("PEFTLORA",),
+ }
+ }
+
+ RETURN_TYPES = ("FL2MODEL",)
+ RETURN_NAMES = ("florence2_model",)
+ FUNCTION = "loadmodel"
+ CATEGORY = "Florence2"
+
+ def loadmodel(self, model, precision, attention, lora=None):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["Florence2ModelLoader"]()
+ return original_loader.loadmodel(model, precision, attention, lora)
+
+class DownloadAndLoadFlorence2Model:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {"required": {
+ "model": (
+ [
+ 'microsoft/Florence-2-base',
+ 'microsoft/Florence-2-base-ft',
+ 'microsoft/Florence-2-large',
+ 'microsoft/Florence-2-large-ft',
+ 'HuggingFaceM4/Florence-2-DocVQA',
+ 'thwri/CogFlorence-2.1-Large',
+ 'thwri/CogFlorence-2.2-Large',
+ 'gokaygokay/Florence-2-SD3-Captioner',
+ 'gokaygokay/Florence-2-Flux-Large',
+ 'MiaoshouAI/Florence-2-base-PromptGen-v1.5',
+ 'MiaoshouAI/Florence-2-large-PromptGen-v1.5',
+ 'MiaoshouAI/Florence-2-base-PromptGen-v2.0',
+ 'MiaoshouAI/Florence-2-large-PromptGen-v2.0'
+ ],
+ {
+ "default": 'microsoft/Florence-2-base'
+ }),
+ "precision": ([ 'fp16','bf16','fp32'],
+ {
+ "default": 'fp16'
+ }),
+ "attention": (
+ [ 'flash_attention_2', 'sdpa', 'eager'],
+ {
+ "default": 'sdpa'
+ }),
+ },
+ "optional": {
+ "lora": ("PEFTLORA",),
+ }
+ }
+
+ RETURN_TYPES = ("FL2MODEL",)
+ RETURN_NAMES = ("florence2_model",)
+ FUNCTION = "loadmodel"
+ CATEGORY = "Florence2"
+
+ def loadmodel(self, model, precision, attention, lora=None):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["DownloadAndLoadFlorence2Model"]()
+ return original_loader.loadmodel(model, precision, attention, lora)
+
+class CheckpointLoaderNF4:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {"required": { "ckpt_name": (folder_paths.get_filename_list("checkpoints"), ),
+ }}
+ RETURN_TYPES = ("MODEL", "CLIP", "VAE")
+ FUNCTION = "load_checkpoint"
+
+ CATEGORY = "loaders"
+
+
+ def load_checkpoint(self, ckpt_name):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["CheckpointLoaderNF4"]()
+ return original_loader.load_checkpoint(ckpt_name)
+
+class LoadFluxControlNet:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {"required": {"model_name": (["flux-dev", "flux-dev-fp8", "flux-schnell"],),
+ "controlnet_path": (folder_paths.get_filename_list("xlabs_controlnets"), ),
+ }}
+
+ RETURN_TYPES = ("FluxControlNet",)
+ RETURN_NAMES = ("ControlNet",)
+ FUNCTION = "loadmodel"
+ CATEGORY = "XLabsNodes"
+
+ def loadmodel(self, model_name, controlnet_path):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["LoadFluxControlNet"]()
+ return original_loader.loadmodel(model_name, controlnet_path)
+
+class MMAudioModelLoader:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "mmaudio_model": (folder_paths.get_filename_list("mmaudio"), {"tooltip": "These models are loaded from the 'ComfyUI/models/mmaudio' -folder",}),
+
+ "base_precision": (["fp16", "fp32", "bf16"], {"default": "fp16"}),
+ },
+ }
+
+ RETURN_TYPES = ("MMAUDIO_MODEL",)
+ RETURN_NAMES = ("mmaudio_model", )
+ FUNCTION = "loadmodel"
+ CATEGORY = "MMAudio"
+
+ def loadmodel(self, mmaudio_model, base_precision):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["MMAudioModelLoader"]()
+ return original_loader.loadmodel(mmaudio_model, base_precision)
+
+class MMAudioFeatureUtilsLoader:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "vae_model": (folder_paths.get_filename_list("mmaudio"), {"tooltip": "These models are loaded from 'ComfyUI/models/mmaudio'"}),
+ "synchformer_model": (folder_paths.get_filename_list("mmaudio"), {"tooltip": "These models are loaded from 'ComfyUI/models/mmaudio'"}),
+ "clip_model": (folder_paths.get_filename_list("mmaudio"), {"tooltip": "These models are loaded from 'ComfyUI/models/mmaudio'"}),
+ },
+ "optional": {
+ "bigvgan_vocoder_model": ("VOCODER_MODEL", {"tooltip": "These models are loaded from 'ComfyUI/models/mmaudio'"}),
+ "mode": (["16k", "44k"], {"default": "44k"}),
+ "precision": (["fp16", "fp32", "bf16"],
+ {"default": "fp16"}
+ ),
+ }
+ }
+
+ RETURN_TYPES = ("MMAUDIO_FEATUREUTILS",)
+ RETURN_NAMES = ("mmaudio_featureutils", )
+ FUNCTION = "loadmodel"
+ CATEGORY = "MMAudio"
+
+ def loadmodel(self, vae_model, precision, synchformer_model, clip_model, mode, bigvgan_vocoder_model=None):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["MMAudioFeatureUtilsLoader"]()
+ return original_loader.loadmodel(vae_model, precision, synchformer_model, clip_model, mode, bigvgan_vocoder_model)
+
+class MMAudioSampler:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "mmaudio_model": ("MMAUDIO_MODEL",),
+ "feature_utils": ("MMAUDIO_FEATUREUTILS",),
+ "duration": ("FLOAT", {"default": 8, "step": 0.01, "tooltip": "Duration of the audio in seconds"}),
+ "steps": ("INT", {"default": 25, "step": 1, "tooltip": "Number of steps to interpolate"}),
+ "cfg": ("FLOAT", {"default": 4.5, "step": 0.1, "tooltip": "Strength of the conditioning"}),
+ "seed": ("INT", {"default": 0, "min": 0, "max": 0xffffffffffffffff}),
+ "prompt": ("STRING", {"default": "", "multiline": True} ),
+ "negative_prompt": ("STRING", {"default": "", "multiline": True} ),
+ "mask_away_clip": ("BOOLEAN", {"default": False, "tooltip": "If true, the clip video will be masked away"}),
+ "force_offload": ("BOOLEAN", {"default": True, "tooltip": "If true, the model will be offloaded to the offload device"}),
+ },
+ "optional": {
+ "images": ("IMAGE",),
+ },
+ }
+
+ RETURN_TYPES = ("AUDIO",)
+ RETURN_NAMES = ("audio", )
+ FUNCTION = "sample"
+ CATEGORY = "MMAudio"
+
+ def sample(self, mmaudio_model, seed, feature_utils, duration, steps, cfg, prompt, negative_prompt, mask_away_clip, force_offload, images=None):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["MMAudioSampler"]()
+ return original_loader.sample(mmaudio_model, seed, feature_utils, duration, steps, cfg, prompt, negative_prompt, mask_away_clip, force_offload, images)
+
+class PulidModelLoader:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {"required": { "pulid_file": (folder_paths.get_filename_list("pulid"), )}}
+
+ RETURN_TYPES = ("PULID",)
+ FUNCTION = "load_model"
+ CATEGORY = "pulid"
+
+ def load_model(self, pulid_file):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["PulidModelLoader"]()
+ return original_loader.load_model(pulid_file)
+
+class PulidInsightFaceLoader:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "provider": (["CPU", "CUDA", "ROCM", "CoreML"], ),
+ },
+ }
+
+ RETURN_TYPES = ("FACEANALYSIS",)
+ FUNCTION = "load_insightface"
+ CATEGORY = "pulid"
+
+ def load_insightface(self, provider):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["PulidInsightFaceLoader"]()
+ return original_loader.load_insightface(provider)
+
+class PulidEvaClipLoader:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {},
+ }
+
+ RETURN_TYPES = ("EVA_CLIP",)
+ FUNCTION = "load_eva_clip"
+ CATEGORY = "pulid"
+
+ def load_eva_clip(self):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["PulidEvaClipLoader"]()
+ return original_loader.load_eva_clip()
+
+
+class HyVideoModelLoader:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "model": (folder_paths.get_filename_list("diffusion_models"), {"tooltip": "These models are loaded from the 'ComfyUI/models/diffusion_models' -folder",}),
+ "base_precision": (["fp32", "bf16"], {"default": "bf16"}),
+ "quantization": (['disabled', 'fp8_e4m3fn', 'fp8_e4m3fn_fast', 'fp8_scaled', 'torchao_fp8dq', "torchao_fp8dqrow", "torchao_int8dq", "torchao_fp6", "torchao_int4", "torchao_int8"], {"default": 'disabled', "tooltip": "optional quantization method"}),
+ "load_device": (["main_device"], {"default": "main_device"}),
+ },
+ "optional": {
+ "attention_mode": ([
+ "sdpa",
+ "flash_attn_varlen",
+ "sageattn_varlen",
+ "comfy",
+ ], {"default": "flash_attn"}),
+ "compile_args": ("COMPILEARGS", ),
+ "block_swap_args": ("BLOCKSWAPARGS", ),
+ "lora": ("HYVIDLORA", {"default": None}),
+ "auto_cpu_offload": ("BOOLEAN", {"default": False, "tooltip": "Enable auto offloading for reduced VRAM usage, implementation from DiffSynth-Studio, slightly different from block swapping and uses even less VRAM, but can be slower as you can't define how much VRAM to use"}),
+ }
+ }
+
+ RETURN_TYPES = ("HYVIDEOMODEL",)
+ RETURN_NAMES = ("model", )
+ FUNCTION = "loadmodel"
+ CATEGORY = "HunyuanVideoWrapper"
+
+ def loadmodel(self, model, base_precision, load_device, quantization, compile_args=None, attention_mode="sdpa", block_swap_args=None, lora=None, auto_cpu_offload=False):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["HyVideoModelLoader"]()
+ return original_loader.loadmodel(model, base_precision, load_device, quantization, compile_args, attention_mode, block_swap_args, lora, auto_cpu_offload)
+
+class HyVideoVAELoader:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "model_name": (folder_paths.get_filename_list("vae"), {"tooltip": "These models are loaded from 'ComfyUI/models/vae'"}),
+ },
+ "optional": {
+ "precision": (["fp16", "fp32", "bf16"],
+ {"default": "bf16"}
+ ),
+ "compile_args":("COMPILEARGS", ),
+ }
+ }
+
+ RETURN_TYPES = ("VAE",)
+ RETURN_NAMES = ("vae", )
+ FUNCTION = "loadmodel"
+ CATEGORY = "HunyuanVideoWrapper"
+ DESCRIPTION = "Loads Hunyuan VAE model from 'ComfyUI/models/vae'"
+
+ def loadmodel(self, model_name, precision, compile_args=None):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["HyVideoVAELoader"]()
+ return original_loader.loadmodel(model_name, precision, compile_args)
+
+class DownloadAndLoadHyVideoTextEncoder:
+ @classmethod
+ def INPUT_TYPES(s):
+ return {
+ "required": {
+ "llm_model": (["Kijai/llava-llama-3-8b-text-encoder-tokenizer","xtuner/llava-llama-3-8b-v1_1-transformers"],),
+ "clip_model": (["disabled","openai/clip-vit-large-patch14",],),
+ "precision": (["fp16", "fp32", "bf16"],
+ {"default": "bf16"}
+ ),
+ },
+ "optional": {
+ "apply_final_norm": ("BOOLEAN", {"default": False}),
+ "hidden_state_skip_layer": ("INT", {"default": 2}),
+ "quantization": (['disabled', 'bnb_nf4', "fp8_e4m3fn"], {"default": 'disabled'}),
+ }
+ }
+
+ RETURN_TYPES = ("HYVIDTEXTENCODER",)
+ RETURN_NAMES = ("hyvid_text_encoder", )
+ FUNCTION = "loadmodel"
+ CATEGORY = "HunyuanVideoWrapper"
+ DESCRIPTION = "Loads Hunyuan text_encoder model from 'ComfyUI/models/LLM'"
+
+ def loadmodel(self, llm_model, clip_model, precision, apply_final_norm=False, hidden_state_skip_layer=2, quantization="disabled"):
+ from nodes import NODE_CLASS_MAPPINGS
+ original_loader = NODE_CLASS_MAPPINGS["DownloadAndLoadHyVideoTextEncoder"]()
+ return original_loader.loadmodel(llm_model, clip_model, precision, apply_final_norm, hidden_state_skip_layer, quantization)
\ No newline at end of file
diff --git a/precompiled_binaries/linux/llama-quantize b/precompiled_binaries/linux/llama-quantize
new file mode 100755
index 0000000..04708cb
Binary files /dev/null and b/precompiled_binaries/linux/llama-quantize differ
diff --git a/precompiled_binaries/win64/llama-quantize.exe b/precompiled_binaries/win64/llama-quantize.exe
new file mode 100755
index 0000000..6c0eb2c
Binary files /dev/null and b/precompiled_binaries/win64/llama-quantize.exe differ