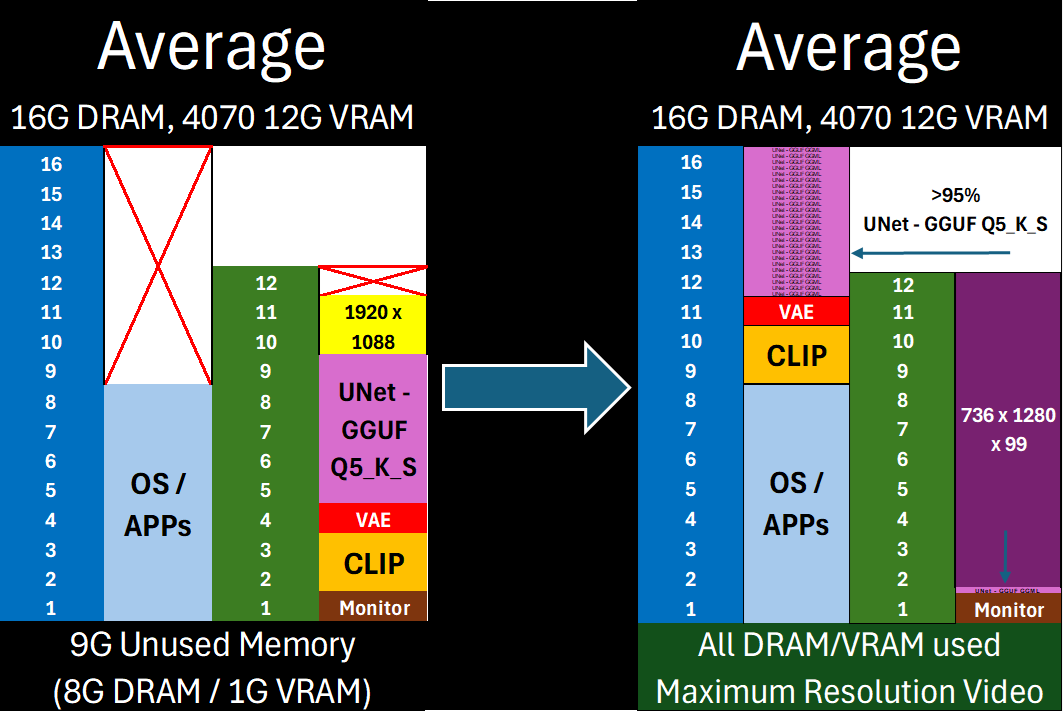
Free almost all of your GPU for what matters: Maximum latent space processing
Free almost all of your GPU for what matters: Maximum latent space processing
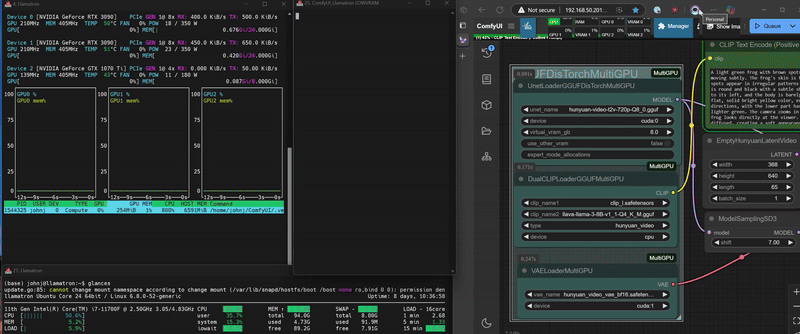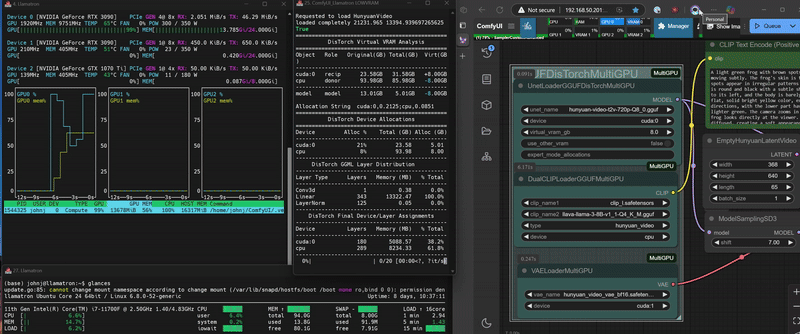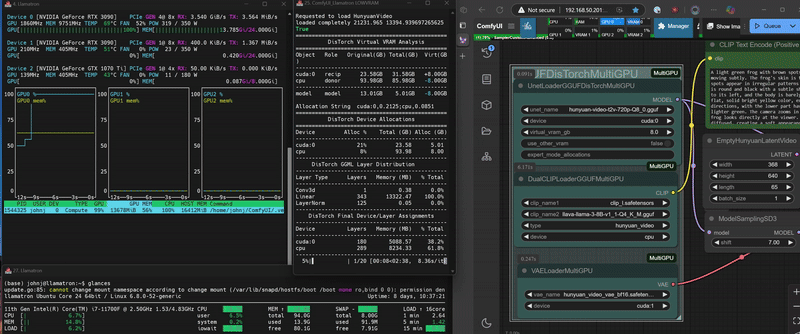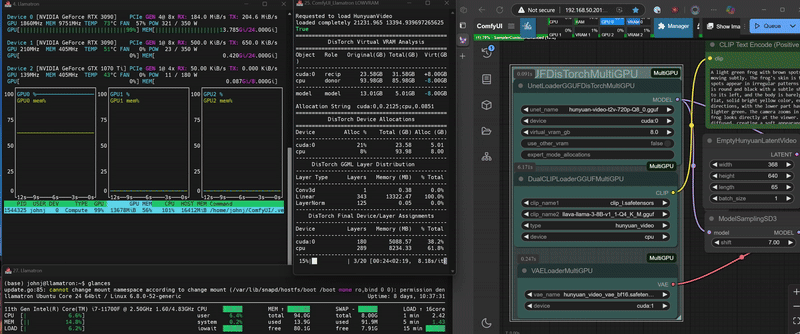 @@ -47,45 +20,30 @@ ComfyUI-MultiGPU now includes a custom, tightly integrated implementation for Wa
DisTorch 2.0 in Action
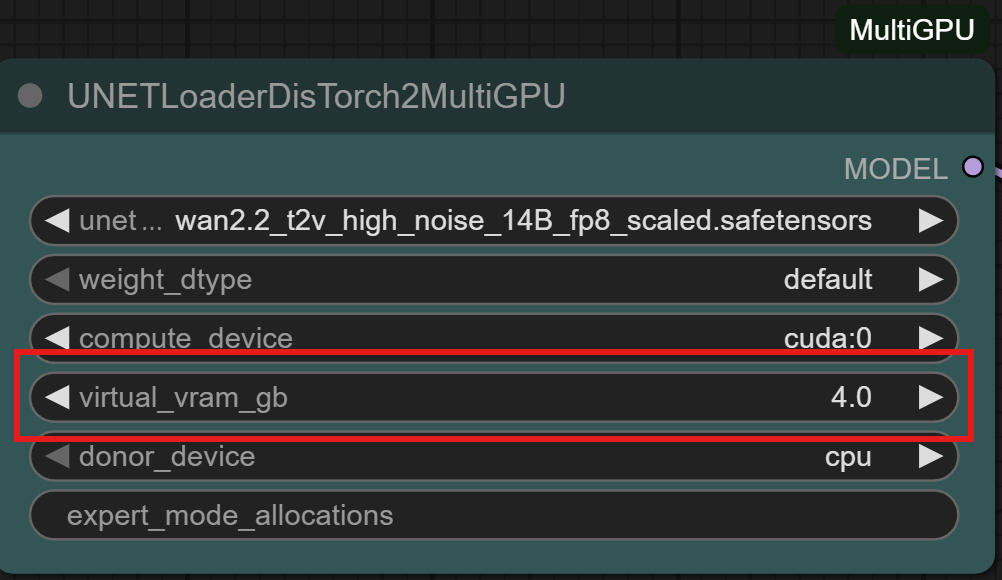
- DisTorch 2.0 Node with one simple number to tune its Vitual VRAM to your needs
+ DisTorch Nodes with one simple number to tune its Vitual VRAM to your needs
 @@ -108,15 +66,23 @@ The extension automatically creates MultiGPU versions of loader nodes. Each Mult
Currently supported nodes (automatically detected if available):
- Standard [ComfyUI](https://github.com/comfyanonymous/ComfyUI) model loaders:
- - CheckpointLoaderSimpleMultiGPU
+ - CheckpointLoaderSimpleMultiGPU/CheckpointLoaderSimpleDistorch2MultiGPU
- CLIPLoaderMultiGPU
- ControlNetLoaderMultiGPU
- DualCLIPLoaderMultiGPU
- TripleCLIPLoaderMultiGPU
- - UNETLoaderMultiGPU
+ - UNETLoaderMultiGPU/UNETLoaderDisTorch2MultiGPU, and
- VAELoaderMultiGPU
+- WanVideoWrapper (requires [ComfyUI-WanVideoWrapper](https://github.com/kijai/ComfyUI-WanVideoWrapper)):
+ - WanVideoModelLoaderMultiGPU & WanVideoModelLoaderMultiGPU_2
+ - WanVideoVAELoaderMultiGPU
+ - LoadWanVideoT5TextEncoderMultiGPU
+ - LoadWanVideoClipTextEncoderMultiGPU
+ - WanVideoTextEncodeMultiGPU
+ - WanVideoBlockSwapMultiGPU
+ - WanVideoSamplerMultiGPU
- GGUF loaders (requires [ComfyUI-GGUF](https://github.com/city96/ComfyUI-GGUF)):
- - UnetLoaderGGUFMultiGPU (supports quantized models like [flux1-dev-gguf](https://huggingface.co/city96/FLUX.1-dev-gguf))
+ - UnetLoaderGGUFMultiGPU/UnetLoaderGGUFDisTorch2MultiGPU
- UnetLoaderGGUFAdvancedMultiGPU
- CLIPLoaderGGUFMultiGPU
- DualCLIPLoaderGGUFMultiGPU
@@ -134,17 +100,6 @@ Currently supported nodes (automatically detected if available):
- HyVideoModelLoaderMultiGPU
- HyVideoVAELoaderMultiGPU
- DownloadAndLoadHyVideoTextEncoderMultiGPU
-- WanVideoWrapper (requires [ComfyUI-WanVideoWrapper](https://github.com/kijai/ComfyUI-WanVideoWrapper)):
- - WanVideoModelLoaderMultiGPU & WanVideoModelLoaderMultiGPU_2
- - WanVideoVAELoaderMultiGPU
- - LoadWanVideoT5TextEncoderMultiGPU
- - LoadWanVideoClipTextEncoderMultiGPU
- - WanVideoTextEncodeMultiGPU
- - WanVideoBlockSwapMultiGPU
- - WanVideoSamplerMultiGPU
-- **Native to ComfyUI-MultiGPU**
- - DeviceSelectorMultiGPU - Allows user to link loaders together to use the same selected device
- - HunyuanVideoEmbeddingsAdapter - Allows Kijai's excellent IP2V CLIP for HunyuanVideo to be used with Comfy Core sampler.
All MultiGPU nodes available for your install can be found in the "multigpu" category in the node menu.
@@ -152,94 +107,46 @@ All MultiGPU nodes available for your install can be found in the "multigpu" cat
All workflows have been tested on a 2x 3090 + 1060ti linux setup, a 4070 win 11 setup, and a 3090/1070ti linux setup.
-### Split WAN2.2 High and Low models on different GPUs while Block Swapping to a third GPU ###
+### DisTorch2
-- [examples/wanvideo2_2_I2V_A14B_example_WIP_MultiGPU.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/wanvideo2_2_I2V_A14B_example_WIP_MultiGPU.json)
- This workflow extends Kijai's I2V example for WanVideo 2.2, demonstrating a dual-model setup. The HIGH model is loaded on `cuda:0`, the LOW model on `cuda:1`, with block-swapping offloaded to `cuda:2`.
+- [Default DisTorch2 Workflow](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/distorch2/default_DisTorch2.json)
+- [FLUX.1-dev Example](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/distorch2/flux_dev_example_DisTorch2.json)
+- [Hunyuan GGUF Example](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/distorch2/hunyuan_gguf_DisTorch2.json)
+- [LTX Video Text-to-Video](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/distorch2/ltxv_text_to_video_MultiGPU.json)
+- [Qwen Image Basic Example](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/distorch2/qwen_image_basic_example_DisTorch2.json)
+- [WanVideo 2.2 Example](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/distorch2/wan2_2_example_DisTorch2.json)
-### Split GGUF-quantized UNet and CLIP models across multiple devices using DisTorch
+### WanVideoWrapper
-- [hunyuan_ip2v_distorch_gguf.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/hunyuan_ip2v_distorch_gguf.json)
-This workflow attaches a HunyuanVideo GGUF-quantized model on `cuda:0` for compute and distrubutes its UNet across itself and the `cpu`. Kijai's IP2V clip loader is loaded on the `cpu`. While the VAE is loaded on GPU 1 directly and uses `cuda:1` for compute.
+- [WanVideo T2V Example](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/wannvideowrapper/wanvideo_T2V_example_MultiGPU.json)
+- [WanVideo 2.2 I2V Example](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/wannvideowrapper/wanvideo2_2_I2V_A14B_example_WIP_Multigpu.json)
-- [examples/hunyuan_gguf_distorch.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/hunyuan_gguf_distorch.json)
-This workflow attaches a HunyuanVideo GGUF-quantized model on `cuda:0` for compute and distrubutes its UNet across itself, a secondary CUDA device, and the system's main memory (`cpu`) using a new DisTorch distributed-load methodology. The text encoder now attaches itself to `cuda:1` and splits iteself between `cuda:1` amd `cpu` layers. While the VAE is loaded on GPU 1 directly and uses `cuda:1` for compute.
+### MultiGPU
-- [examples/flux1dev_gguf_distorch.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/flux1dev_gguf_distorch.json)
-This workflow loads a FLUX.1-dev model on `cuda:0` for compute and distrubutes its UNet across multiple CUDA devices using new DisTorch distributed-load methodology. While the text encoders and VAE are loaded on GPU 1 and use `cuda:1` for compute.
+- [FLUX.1-dev Example](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/multiGPU/flux_dev_example_MultiGPU.json)
+- [SDXL 2-GPU](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/multiGPU/sdxl_2gpu.json)
-### Split Wan Video generation across multiple resources
+### Florence2
-- [examples/hunyuanvideowrapper_native_vae.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/wanvideo_T2V_example_MultiGPU.json)
-This workflow is a simple extension of [kijai's T2V example](https://github.com/kijai/ComfyUI-WanVideoWrapper/blob/main/example_workflows/wanvideo_T2V_example_02.json) from his custom_node.
+- [Florence2, FLUX.1-dev, LTX Video Pipeline](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/florence2/florence2_flux1dev_ltxv_cpu_2gpu.json)
-### Split Hunyuan Video generation across multiple resources
+### GGUF
-- [examples/hunyuanvideowrapper_native_vae.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/hunyuanvideowrapper_native_vae.json)
-This workflow uses two of the custom_node's loaders - putting the main video model on cuda0 and the CLIP onto the CPU. This workflow uses Comfy's native VAE loader to load the VAE onto a second cuda device, keeping model, VAE, and CLIP in their operating memory space at all times. This allows the benefit of kijai's proecessing node with the flexibility of a MultiGPU setup.
+- [FLUX.1-dev 2-GPU GGUF](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/gguf/flux1dev_2gpu_gguf.json)
+- [Hunyuan 2-GPU GGUF](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/gguf/hunyuan_2gpu_gguf.json)
+- [Hunyuan CPU+GPU GGUF](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/gguf/hunyuan_cpu_1gpu_gguf.json)
+- [Hunyuan GGUF DisTorch](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/gguf/hunyuan_gguf_distorch.json)
+- [Hunyuan GGUF MultiGPU](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/gguf/hunyuan_gguf_MultiGPU.json)
-- [examples/hunyuanvideowrapper_select_device.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/hunyuanvideowrapper_select_device.json)
-This workflow loads the main video model and VAE onto the cuda device and the CLIP onto the cpu. The model and VAE are linked in this example due to kijai's own extensive memory management assuming model and VAE are on the same device.
+### HunyuanVideoWrapper
-### Split FLUX.1-dev across two GPUs
+- [HunyuanVideoWrapper Native VAE](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/hunyuanvideowrapper/hunyuanvideowrapper_native_vae.json)
+- [HunyuanVideoWrapper Select Device](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/hunyuanvideowrapper/hunyuanvideowrapper_select_device.json)
-- [examples/flux1dev_2gpu.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/flux1dev_2gpu.json)
-This workflow loads a FLUX.1-dev model and splits its components across two GPUs. The UNet model is loaded on GPU 1 while the text encoders and VAE are loaded on GPU 0.
+### DisTorch (Legacy GGUF)
-### Split FLUX.1-dev between the CPU and a single GPU
-
-- [examples/flux1dev_cpu_1gpu_GGUF.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/flux1dev_cpu_1gpu_GGUF.json)
-This workflow demonstrates splitting a quantized, GGUF FLUX.1-dev model between a CPU and a single GPU. The UNet model is loaded on the GPU, while the VAE and text encoders are handled by the CPU. Requires [ComfyUI-GGUF](https://github.com/city96/ComfyUI-GGUF).
-
-### Using GGUF quantized models across GPUs
-
-- [examples/flux1dev_2gpu_GGUF.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/flux1dev_2gpu_GGUF.json)
-This workflow demonstrates using quantized GGUF models split across multiple GPUs for reduced VRAM usage with the UNet on GPU 1, VAE and text encoders on GPU 0. Requires [ComfyUI-GGUF](https://github.com/city96/ComfyUI-GGUF).
-
-### Using GGUF quantized models across a CPU and a single GPU for video generation
-
-- [examples/hunyuan_cpu_1gpu_GGUF.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/hunyuan_cpu_1gpu_GGUF.json)
-This workflow demonstrates using quantized GGUF models for Hunyan Video split across the CPU and one GPU. In this instance, a quantized video model's UNet and VAE are on GPU 0, whereas a split of one standard and one GGUF model text encoder are on the CPU. Requires [ComfyUI-GGUF](https://github.com/city96/ComfyUI-GGUF).
-
-### Using GGUF quantized models across GPUs for video generation
-
-- [examples/hunyuan_2gpu_GGUF.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/hunyuan_2gpu_GGUF.json)
-This workflow demonstrates using quantized GGUF models for Hunyan Video split across multiple GPUs. In this instance, a quantized video model's UNet is on GPU 0 whereas the VAE and text encoders are on GPU 1. Requires [ComfyUI-GGUF](https://github.com/city96/ComfyUI-GGUF).
-
-### Loading two SDXL checkpoints on different GPUs
-
-- [examples/sdxl_2gpu.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/sdxl_2gpu.json)
-This workflow loads two SDXL checkpoints on two different GPUs. The first checkpoint is loaded on GPU 0, and the second checkpoint is loaded on GPU 1.
-
-### FLUX.1-dev and SDXL in the same workflow
-
-- [examples/flux1dev_sdxl_2gpu.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/flux1dev_sdxl_2gpu.json)
-This workflow loads a FLUX.1-dev model and an SDXL model in the same workflow. The FLUX.1-dev model has its UNet on GPU 1 with VAE and text encoders on GPU 0, while the SDXL model uses separate allocations on GPU 0.
-
-### Image to Prompt to Image to Video Generation Pipeline
-
-- [examples/florence2_flux1dev_ltxv_cpu_2gpu.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/florence2_flux1dev_ltxv_cpu_2gpu.json)
-This workflow creates an img2txt2img2vid video generation pipeline by:
-
- 1. Loading the Florence2 model on the CPU and providing a starting image for analysis and generating a text response
- 2. Loading FLUX.1 Dev UNET on GPU 1, with CLIP and VAE on the CPU and generating an image using the Florence2 text as a prompt
- 3. Loading the LTX Video UNet and VAE on GPU 2, and LTX-encoded CLIP on the CPU, and taking the resulting FLUX.1 image and provide it as the starting image for an LTX Video image-to-video generation
- 4. Generate a 5 second video based on the provided image
-All models are distributed across available the available CPU and GPUs with no model reloading on dual 3090s. Requires [ComfyUI-GGUF](https://github.com/city96/ComfyUI-GGUF) and [ComfyUI-LTXVideo](https://github.com/Lightricks/ComfyUI-LTXVideo)
-
-### Using DeviceSelectorMultiGPU
-
-- [examples/device_selector_lowvram_flux_controlnet.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/device_selector_lowvram_flux_controlnet.json)
-This workflow loads a GGUF version of FLUX.1-dev onto a cuda device and the T5 CLIP onto the CPU. The FLUX.1-dev fill controlnet model by alimama-creative [FLUX.1-dev-Controlnet-Inpainting-Alpha controlnet model](https://huggingface.co/alimama-creative/FLUX.1-dev-Controlnet-Inpainting-Alpha/tree/main) illustrating linking two loaders together so their resources always remain in-sync.
-
-#### LLM-Guided Video Generation
-
-- [examples/llamacpp_ltxv_2gpu_GGUF.json](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/llamacpp_ltxv_2gpu_GGUF.json)
-This workflow demonstrates:
-
-1. Using a local LLM (loaded on first GPU via llama.cpp) to take a text suggestion and craft an LTX Video prompt
-2. Feeding the enhanced prompt to LTXVideo (loaded on second GPU) for video generation
-Requires appropriate LLM. Requires [ComfyUI-GGUF](https://github.com/city96/ComfyUI-GGUF).
+- [FLUX.1-dev GGUF DisTorch](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/distorch/flux1dev_gguf_distorch.json)
+- [Hunyuan IP2V GGUF DisTorch](https://github.com/pollockjj/ComfyUI-MultiGPU/blob/main/examples/distorch/hunyuan_ip2v_distorch_gguf.json)
## Support
@@ -247,6 +154,6 @@ If you encounter problems, please [open an issue](https://github.com/pollockjj/C
## Credits
-Originally created by [Alexander Dzhoganov](https://github.com/AlexanderDzhoganov).
-Implementation improved by [City96](https://v100s.net/).
Currently maintained by [pollockjj](https://github.com/pollockjj).
+Originally created by [Alexander Dzhoganov](https://github.com/AlexanderDzhoganov).
+With deepest thanks to [City96](https://v100s.net/).
\ No newline at end of file
diff --git a/assets/distorch2_0.png b/assets/distorch2_0.png
index 31ce659..2c42a00 100755
Binary files a/assets/distorch2_0.png and b/assets/distorch2_0.png differ
diff --git a/assets/distorch_node.png b/assets/distorch_node.png
index 8c403e9..eb9d22e 100755
Binary files a/assets/distorch_node.png and b/assets/distorch_node.png differ