 storyicon
@@ -0,0 +1,60 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# 조건부 이미지 생성
|
||||
|
||||
[[open-in-colab]]
|
||||
|
||||
조건부 이미지 생성을 사용하면 텍스트 프롬프트에서 이미지를 생성할 수 있습니다. 텍스트는 임베딩으로 변환되며, 임베딩은 노이즈에서 이미지를 생성하도록 모델을 조건화하는 데 사용됩니다.
|
||||
|
||||
[`DiffusionPipeline`]은 추론을 위해 사전 훈련된 diffusion 시스템을 사용하는 가장 쉬운 방법입니다.
|
||||
|
||||
먼저 [`DiffusionPipeline`]의 인스턴스를 생성하고 다운로드할 파이프라인 [체크포인트](https://huggingface.co/models?library=diffusers&sort=downloads)를 지정합니다.
|
||||
|
||||
이 가이드에서는 [잠재 Diffusion](https://huggingface.co/CompVis/ldm-text2im-large-256)과 함께 텍스트-이미지 생성에 [`DiffusionPipeline`]을 사용합니다:
|
||||
|
||||
```python
|
||||
>>> from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
>>> generator = DiffusionPipeline.from_pretrained("CompVis/ldm-text2im-large-256")
|
||||
```
|
||||
|
||||
[`DiffusionPipeline`]은 모든 모델링, 토큰화, 스케줄링 구성 요소를 다운로드하고 캐시합니다.
|
||||
이 모델은 약 14억 개의 파라미터로 구성되어 있기 때문에 GPU에서 실행할 것을 강력히 권장합니다.
|
||||
PyTorch에서와 마찬가지로 생성기 객체를 GPU로 이동할 수 있습니다:
|
||||
|
||||
```python
|
||||
>>> generator.to("cuda")
|
||||
```
|
||||
|
||||
이제 텍스트 프롬프트에서 `생성기`를 사용할 수 있습니다:
|
||||
|
||||
```python
|
||||
>>> image = generator("An image of a squirrel in Picasso style").images[0]
|
||||
```
|
||||
|
||||
출력값은 기본적으로 [`PIL.Image`](https://pillow.readthedocs.io/en/stable/reference/Image.html?highlight=image#the-image-class) 객체로 래핑됩니다.
|
||||
|
||||
호출하여 이미지를 저장할 수 있습니다:
|
||||
|
||||
```python
|
||||
>>> image.save("image_of_squirrel_painting.png")
|
||||
```
|
||||
|
||||
아래 스페이스를 사용해보고 안내 배율 매개변수를 자유롭게 조정하여 이미지 품질에 어떤 영향을 미치는지 확인해 보세요!
|
||||
|
||||
<iframe
|
||||
src="https://stabilityai-stable-diffusion.hf.space"
|
||||
frameborder="0"
|
||||
width="850"
|
||||
height="500"
|
||||
></iframe>
|
||||
@@ -0,0 +1,182 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# 커뮤니티 파이프라인에 기여하는 방법
|
||||
|
||||
<Tip>
|
||||
|
||||
💡 모든 사람이 속도 저하 없이 쉽게 작업을 공유할 수 있도록 커뮤니티 파이프라인을 추가하는 이유에 대한 자세한 내용은 GitHub 이슈 [#841](https://github.com/huggingface/diffusers/issues/841)를 참조하세요.
|
||||
|
||||
</Tip>
|
||||
|
||||
커뮤니티 파이프라인을 사용하면 [`DiffusionPipeline`] 위에 원하는 추가 기능을 추가할 수 있습니다. `DiffusionPipeline` 위에 구축할 때의 가장 큰 장점은 누구나 인수를 하나만 추가하면 파이프라인을 로드하고 사용할 수 있어 커뮤니티가 매우 쉽게 접근할 수 있다는 것입니다.
|
||||
|
||||
이번 가이드에서는 커뮤니티 파이프라인을 생성하는 방법과 작동 원리를 설명합니다.
|
||||
간단하게 설명하기 위해 `UNet`이 단일 forward pass를 수행하고 스케줄러를 한 번 호출하는 "one-step" 파이프라인을 만들겠습니다.
|
||||
|
||||
## 파이프라인 초기화
|
||||
|
||||
커뮤니티 파이프라인을 위한 `one_step_unet.py` 파일을 생성하는 것으로 시작합니다. 이 파일에서, Hub에서 모델 가중치와 스케줄러 구성을 로드할 수 있도록 [`DiffusionPipeline`]을 상속하는 파이프라인 클래스를 생성합니다. one-step 파이프라인에는 `UNet`과 스케줄러가 필요하므로 이를 `__init__` 함수에 인수로 추가해야합니다:
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
import torch
|
||||
|
||||
|
||||
class UnetSchedulerOneForwardPipeline(DiffusionPipeline):
|
||||
def __init__(self, unet, scheduler):
|
||||
super().__init__()
|
||||
```
|
||||
|
||||
파이프라인과 그 구성요소(`unet` and `scheduler`)를 [`~DiffusionPipeline.save_pretrained`]으로 저장할 수 있도록 하려면 `register_modules` 함수에 추가하세요:
|
||||
|
||||
```diff
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
import torch
|
||||
|
||||
class UnetSchedulerOneForwardPipeline(DiffusionPipeline):
|
||||
def __init__(self, unet, scheduler):
|
||||
super().__init__()
|
||||
|
||||
+ self.register_modules(unet=unet, scheduler=scheduler)
|
||||
```
|
||||
|
||||
이제 '초기화' 단계가 완료되었으니 forward pass로 이동할 수 있습니다! 🔥
|
||||
|
||||
## Forward pass 정의
|
||||
|
||||
Forward pass 에서는(`__call__`로 정의하는 것이 좋습니다) 원하는 기능을 추가할 수 있는 완전한 창작 자유가 있습니다. 우리의 놀라운 one-step 파이프라인의 경우, 임의의 이미지를 생성하고 `timestep=1`을 설정하여 `unet`과 `scheduler`를 한 번만 호출합니다:
|
||||
|
||||
```diff
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
import torch
|
||||
|
||||
|
||||
class UnetSchedulerOneForwardPipeline(DiffusionPipeline):
|
||||
def __init__(self, unet, scheduler):
|
||||
super().__init__()
|
||||
|
||||
self.register_modules(unet=unet, scheduler=scheduler)
|
||||
|
||||
+ def __call__(self):
|
||||
+ image = torch.randn(
|
||||
+ (1, self.unet.config.in_channels, self.unet.config.sample_size, self.unet.config.sample_size),
|
||||
+ )
|
||||
+ timestep = 1
|
||||
|
||||
+ model_output = self.unet(image, timestep).sample
|
||||
+ scheduler_output = self.scheduler.step(model_output, timestep, image).prev_sample
|
||||
|
||||
+ return scheduler_output
|
||||
```
|
||||
|
||||
끝났습니다! 🚀 이제 이 파이프라인에 `unet`과 `scheduler`를 전달하여 실행할 수 있습니다:
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DDPMScheduler, UNet2DModel
|
||||
|
||||
scheduler = DDPMScheduler()
|
||||
unet = UNet2DModel()
|
||||
|
||||
pipeline = UnetSchedulerOneForwardPipeline(unet=unet, scheduler=scheduler)
|
||||
|
||||
output = pipeline()
|
||||
```
|
||||
|
||||
하지만 파이프라인 구조가 동일한 경우 기존 가중치를 파이프라인에 로드할 수 있다는 장점이 있습니다. 예를 들어 one-step 파이프라인에 [`google/ddpm-cifar10-32`](https://huggingface.co/google/ddpm-cifar10-32) 가중치를 로드할 수 있습니다:
|
||||
|
||||
```python
|
||||
pipeline = UnetSchedulerOneForwardPipeline.from_pretrained("google/ddpm-cifar10-32")
|
||||
|
||||
output = pipeline()
|
||||
```
|
||||
|
||||
## 파이프라인 공유
|
||||
|
||||
🧨Diffusers [리포지토리](https://github.com/huggingface/diffusers)에서 Pull Request를 열어 [examples/community](https://github.com/huggingface/diffusers/tree/main/examples/community) 하위 폴더에 `one_step_unet.py`의 멋진 파이프라인을 추가하세요.
|
||||
|
||||
병합이 되면, `diffusers >= 0.4.0`이 설치된 사용자라면 누구나 `custom_pipeline` 인수에 지정하여 이 파이프라인을 마술처럼 🪄 사용할 수 있습니다:
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
pipe = DiffusionPipeline.from_pretrained("google/ddpm-cifar10-32", custom_pipeline="one_step_unet")
|
||||
pipe()
|
||||
```
|
||||
|
||||
커뮤니티 파이프라인을 공유하는 또 다른 방법은 Hub 에서 선호하는 [모델 리포지토리](https://huggingface.co/docs/hub/models-uploading)에 직접 `one_step_unet.py` 파일을 업로드하는 것입니다. `one_step_unet.py` 파일을 지정하는 대신 모델 저장소 id를 `custom_pipeline` 인수에 전달하세요:
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
pipeline = DiffusionPipeline.from_pretrained("google/ddpm-cifar10-32", custom_pipeline="stevhliu/one_step_unet")
|
||||
```
|
||||
|
||||
다음 표에서 두 가지 공유 워크플로우를 비교하여 자신에게 가장 적합한 옵션을 결정하는 데 도움이 되는 정보를 확인하세요:
|
||||
|
||||
| | GitHub 커뮤니티 파이프라인 | HF Hub 커뮤니티 파이프라인 |
|
||||
|----------------|------------------------------------------------------------------------------------------------------------------|-------------------------------------------------------------------------------------------|
|
||||
| 사용법 | 동일 | 동일 |
|
||||
| 리뷰 과정 | 병합하기 전에 GitHub에서 Pull Request를 열고 Diffusers 팀의 검토 과정을 거칩니다. 속도가 느릴 수 있습니다. | 검토 없이 Hub 저장소에 바로 업로드합니다. 가장 빠른 워크플로우 입니다. |
|
||||
| 가시성 | 공식 Diffusers 저장소 및 문서에 포함되어 있습니다. | HF 허브 프로필에 포함되며 가시성을 확보하기 위해 자신의 사용량/프로모션에 의존합니다. |
|
||||
|
||||
<Tip>
|
||||
|
||||
💡 커뮤니티 파이프라인 파일에 원하는 패키지를 사용할 수 있습니다. 사용자가 패키지를 설치하기만 하면 모든 것이 정상적으로 작동합니다. 파이프라인이 자동으로 감지되므로 `DiffusionPipeline`에서 상속하는 파이프라인 클래스가 하나만 있는지 확인하세요.
|
||||
|
||||
</Tip>
|
||||
|
||||
## 커뮤니티 파이프라인은 어떻게 작동하나요?
|
||||
|
||||
커뮤니티 파이프라인은 [`DiffusionPipeline`]을 상속하는 클래스입니다:
|
||||
|
||||
- [`custom_pipeline`] 인수로 로드할 수 있습니다.
|
||||
- 모델 가중치 및 스케줄러 구성은 [`pretrained_model_name_or_path`]에서 로드됩니다.
|
||||
- 커뮤니티 파이프라인에서 기능을 구현하는 코드는 `pipeline.py` 파일에 정의되어 있습니다.
|
||||
|
||||
공식 저장소에서 모든 파이프라인 구성 요소 가중치를 로드할 수 없는 경우가 있습니다. 이 경우 다른 구성 요소는 파이프라인에 직접 전달해야 합니다:
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
from transformers import CLIPFeatureExtractor, CLIPModel
|
||||
|
||||
model_id = "CompVis/stable-diffusion-v1-4"
|
||||
clip_model_id = "laion/CLIP-ViT-B-32-laion2B-s34B-b79K"
|
||||
|
||||
feature_extractor = CLIPFeatureExtractor.from_pretrained(clip_model_id)
|
||||
clip_model = CLIPModel.from_pretrained(clip_model_id, torch_dtype=torch.float16)
|
||||
|
||||
pipeline = DiffusionPipeline.from_pretrained(
|
||||
model_id,
|
||||
custom_pipeline="clip_guided_stable_diffusion",
|
||||
clip_model=clip_model,
|
||||
feature_extractor=feature_extractor,
|
||||
scheduler=scheduler,
|
||||
torch_dtype=torch.float16,
|
||||
)
|
||||
```
|
||||
|
||||
커뮤니티 파이프라인의 마법은 다음 코드에 담겨 있습니다. 이 코드를 통해 커뮤니티 파이프라인을 GitHub 또는 Hub에서 로드할 수 있으며, 모든 🧨 Diffusers 패키지에서 사용할 수 있습니다.
|
||||
|
||||
```python
|
||||
# 2. 파이프라인 클래스를 로드합니다. 사용자 지정 모듈을 사용하는 경우 Hub에서 로드합니다
|
||||
# 명시적 클래스에서 로드하는 경우, 이를 사용해 보겠습니다.
|
||||
if custom_pipeline is not None:
|
||||
pipeline_class = get_class_from_dynamic_module(
|
||||
custom_pipeline, module_file=CUSTOM_PIPELINE_FILE_NAME, cache_dir=custom_pipeline
|
||||
)
|
||||
elif cls != DiffusionPipeline:
|
||||
pipeline_class = cls
|
||||
else:
|
||||
diffusers_module = importlib.import_module(cls.__module__.split(".")[0])
|
||||
pipeline_class = getattr(diffusers_module, config_dict["_class_name"])
|
||||
```
|
||||
@@ -0,0 +1,45 @@
|
||||
# 이미지 밝기 조절하기
|
||||
|
||||
Stable Diffusion 파이프라인은 [일반적인 디퓨전 노이즈 스케줄과 샘플 단계에 결함이 있음](https://huggingface.co/papers/2305.08891) 논문에서 설명한 것처럼 매우 밝거나 어두운 이미지를 생성하는 데는 성능이 평범합니다. 이 논문에서 제안한 솔루션은 현재 [`DDIMScheduler`]에 구현되어 있으며 이미지의 밝기를 개선하는 데 사용할 수 있습니다.
|
||||
|
||||
<Tip>
|
||||
|
||||
💡 제안된 솔루션에 대한 자세한 내용은 위에 링크된 논문을 참고하세요!
|
||||
|
||||
</Tip>
|
||||
|
||||
해결책 중 하나는 *v 예측값*과 *v 로스*로 모델을 훈련하는 것입니다. 다음 flag를 [`train_text_to_image.py`](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image.py) 또는 [`train_text_to_image_lora.py`](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image_lora.py) 스크립트에 추가하여 `v_prediction`을 활성화합니다:
|
||||
|
||||
```bash
|
||||
--prediction_type="v_prediction"
|
||||
```
|
||||
|
||||
예를 들어, `v_prediction`으로 미세 조정된 [`ptx0/pseudo-journey-v2`](https://huggingface.co/ptx0/pseudo-journey-v2) 체크포인트를 사용해 보겠습니다.
|
||||
|
||||
다음으로 [`DDIMScheduler`]에서 다음 파라미터를 설정합니다:
|
||||
|
||||
1. rescale_betas_zero_snr=True`, 노이즈 스케줄을 제로 터미널 신호 대 잡음비(SNR)로 재조정합니다.
|
||||
2. `timestep_spacing="trailing"`, 마지막 타임스텝부터 샘플링 시작
|
||||
|
||||
```py
|
||||
>>> from MuseVdiffusers import DiffusionPipeline, DDIMScheduler
|
||||
|
||||
>>> pipeline = DiffusionPipeline.from_pretrained("ptx0/pseudo-journey-v2")
|
||||
# switch the scheduler in the pipeline to use the DDIMScheduler
|
||||
|
||||
>>> pipeline.scheduler = DDIMScheduler.from_config(
|
||||
... pipeline.scheduler.config, rescale_betas_zero_snr=True, timestep_spacing="trailing"
|
||||
... )
|
||||
>>> pipeline.to("cuda")
|
||||
```
|
||||
|
||||
마지막으로 파이프라인에 대한 호출에서 `guidance_rescale`을 설정하여 과다 노출을 방지합니다:
|
||||
|
||||
```py
|
||||
prompt = "A lion in galaxies, spirals, nebulae, stars, smoke, iridescent, intricate detail, octane render, 8k"
|
||||
image = pipeline(prompt, guidance_rescale=0.7).images[0]
|
||||
```
|
||||
|
||||
<div class="flex justify-center">
|
||||
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/zero_snr.png"/>
|
||||
</div>
|
||||
@@ -0,0 +1,226 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# 제어된 생성
|
||||
|
||||
Diffusion 모델에 의해 생성된 출력을 제어하는 것은 커뮤니티에서 오랫동안 추구해 왔으며 현재 활발한 연구 주제입니다. 널리 사용되는 많은 diffusion 모델에서는 이미지와 텍스트 프롬프트 등 입력의 미묘한 변화로 인해 출력이 크게 달라질 수 있습니다. 이상적인 세계에서는 의미가 유지되고 변경되는 방식을 제어할 수 있기를 원합니다.
|
||||
|
||||
의미 보존의 대부분의 예는 입력의 변화를 출력의 변화에 정확하게 매핑하는 것으로 축소됩니다. 즉, 프롬프트에서 피사체에 형용사를 추가하면 전체 이미지가 보존되고 변경된 피사체만 수정됩니다. 또는 특정 피사체의 이미지를 변형하면 피사체의 포즈가 유지됩니다.
|
||||
|
||||
추가적으로 생성된 이미지의 품질에는 의미 보존 외에도 영향을 미치고자 하는 품질이 있습니다. 즉, 일반적으로 결과물의 품질이 좋거나 특정 스타일을 고수하거나 사실적이기를 원합니다.
|
||||
|
||||
diffusion 모델 생성을 제어하기 위해 `diffusers`가 지원하는 몇 가지 기술을 문서화합니다. 많은 부분이 최첨단 연구이며 미묘한 차이가 있을 수 있습니다. 명확한 설명이 필요하거나 제안 사항이 있으면 주저하지 마시고 [포럼](https://discuss.huggingface.co/) 또는 [GitHub 이슈](https://github.com/huggingface/diffusers/issues)에서 토론을 시작하세요.
|
||||
|
||||
생성 제어 방법에 대한 개략적인 설명과 기술 개요를 제공합니다. 기술에 대한 자세한 설명은 파이프라인에서 링크된 원본 논문을 참조하는 것이 가장 좋습니다.
|
||||
|
||||
사용 사례에 따라 적절한 기술을 선택해야 합니다. 많은 경우 이러한 기법을 결합할 수 있습니다. 예를 들어, 텍스트 반전과 SEGA를 결합하여 텍스트 반전을 사용하여 생성된 출력에 더 많은 의미적 지침을 제공할 수 있습니다.
|
||||
|
||||
별도의 언급이 없는 한, 이러한 기법은 기존 모델과 함께 작동하며 자체 가중치가 필요하지 않은 기법입니다.
|
||||
|
||||
1. [Instruct Pix2Pix](#instruct-pix2pix)
|
||||
2. [Pix2Pix Zero](#pix2pixzero)
|
||||
3. [Attend and Excite](#attend-and-excite)
|
||||
4. [Semantic Guidance](#semantic-guidance)
|
||||
5. [Self-attention Guidance](#self-attention-guidance)
|
||||
6. [Depth2Image](#depth2image)
|
||||
7. [MultiDiffusion Panorama](#multidiffusion-panorama)
|
||||
8. [DreamBooth](#dreambooth)
|
||||
9. [Textual Inversion](#textual-inversion)
|
||||
10. [ControlNet](#controlnet)
|
||||
11. [Prompt Weighting](#prompt-weighting)
|
||||
12. [Custom Diffusion](#custom-diffusion)
|
||||
13. [Model Editing](#model-editing)
|
||||
14. [DiffEdit](#diffedit)
|
||||
15. [T2I-Adapter](#t2i-adapter)
|
||||
|
||||
편의를 위해, 추론만 하거나 파인튜닝/학습하는 방법에 대한 표를 제공합니다.
|
||||
|
||||
| **Method** | **Inference only** | **Requires training /<br> fine-tuning** | **Comments** |
|
||||
| :-------------------------------------------------: | :----------------: | :-------------------------------------: | :---------------------------------------------------------------------------------------------: |
|
||||
| [Instruct Pix2Pix](#instruct-pix2pix) | ✅ | ❌ | Can additionally be<br>fine-tuned for better <br>performance on specific <br>edit instructions. |
|
||||
| [Pix2Pix Zero](#pix2pixzero) | ✅ | ❌ | |
|
||||
| [Attend and Excite](#attend-and-excite) | ✅ | ❌ | |
|
||||
| [Semantic Guidance](#semantic-guidance) | ✅ | ❌ | |
|
||||
| [Self-attention Guidance](#self-attention-guidance) | ✅ | ❌ | |
|
||||
| [Depth2Image](#depth2image) | ✅ | ❌ | |
|
||||
| [MultiDiffusion Panorama](#multidiffusion-panorama) | ✅ | ❌ | |
|
||||
| [DreamBooth](#dreambooth) | ❌ | ✅ | |
|
||||
| [Textual Inversion](#textual-inversion) | ❌ | ✅ | |
|
||||
| [ControlNet](#controlnet) | ✅ | ❌ | A ControlNet can be <br>trained/fine-tuned on<br>a custom conditioning. |
|
||||
| [Prompt Weighting](#prompt-weighting) | ✅ | ❌ | |
|
||||
| [Custom Diffusion](#custom-diffusion) | ❌ | ✅ | |
|
||||
| [Model Editing](#model-editing) | ✅ | ❌ | |
|
||||
| [DiffEdit](#diffedit) | ✅ | ❌ | |
|
||||
| [T2I-Adapter](#t2i-adapter) | ✅ | ❌ | |
|
||||
|
||||
## Pix2Pix Instruct
|
||||
|
||||
[Paper](https://arxiv.org/abs/2211.09800)
|
||||
|
||||
[Instruct Pix2Pix](../api/pipelines/stable_diffusion/pix2pix) 는 입력 이미지 편집을 지원하기 위해 stable diffusion에서 미세-조정되었습니다. 이미지와 편집을 설명하는 프롬프트를 입력으로 받아 편집된 이미지를 출력합니다.
|
||||
Instruct Pix2Pix는 [InstructGPT](https://openai.com/blog/instruction-following/)와 같은 프롬프트와 잘 작동하도록 명시적으로 훈련되었습니다.
|
||||
|
||||
사용 방법에 대한 자세한 내용은 [여기](../api/pipelines/stable_diffusion/pix2pix)를 참조하세요.
|
||||
|
||||
## Pix2Pix Zero
|
||||
|
||||
[Paper](https://arxiv.org/abs/2302.03027)
|
||||
|
||||
[Pix2Pix Zero](../api/pipelines/stable_diffusion/pix2pix_zero)를 사용하면 일반적인 이미지 의미를 유지하면서 한 개념이나 피사체가 다른 개념이나 피사체로 변환되도록 이미지를 수정할 수 있습니다.
|
||||
|
||||
노이즈 제거 프로세스는 한 개념적 임베딩에서 다른 개념적 임베딩으로 안내됩니다. 중간 잠복(intermediate latents)은 디노이징(denoising?) 프로세스 중에 최적화되어 참조 주의 지도(reference attention maps)를 향해 나아갑니다. 참조 주의 지도(reference attention maps)는 입력 이미지의 노이즈 제거(?) 프로세스에서 나온 것으로 의미 보존을 장려하는 데 사용됩니다.
|
||||
|
||||
Pix2Pix Zero는 합성 이미지와 실제 이미지를 편집하는 데 모두 사용할 수 있습니다.
|
||||
|
||||
- 합성 이미지를 편집하려면 먼저 캡션이 지정된 이미지를 생성합니다.
|
||||
다음으로 편집할 컨셉과 새로운 타겟 컨셉에 대한 이미지 캡션을 생성합니다. 이를 위해 [Flan-T5](https://huggingface.co/docs/transformers/model_doc/flan-t5)와 같은 모델을 사용할 수 있습니다. 그런 다음 텍스트 인코더를 통해 소스 개념과 대상 개념 모두에 대한 "평균" 프롬프트 임베딩을 생성합니다. 마지막으로, 합성 이미지를 편집하기 위해 pix2pix-zero 알고리즘을 사용합니다.
|
||||
- 실제 이미지를 편집하려면 먼저 [BLIP](https://huggingface.co/docs/transformers/model_doc/blip)과 같은 모델을 사용하여 이미지 캡션을 생성합니다. 그런 다음 프롬프트와 이미지에 ddim 반전을 적용하여 "역(inverse)" latents을 생성합니다. 이전과 마찬가지로 소스 및 대상 개념 모두에 대한 "평균(mean)" 프롬프트 임베딩이 생성되고 마지막으로 "역(inverse)" latents와 결합된 pix2pix-zero 알고리즘이 이미지를 편집하는 데 사용됩니다.
|
||||
|
||||
<Tip>
|
||||
|
||||
Pix2Pix Zero는 '제로 샷(zero-shot)' 이미지 편집이 가능한 최초의 모델입니다.
|
||||
즉, 이 모델은 다음과 같이 일반 소비자용 GPU에서 1분 이내에 이미지를 편집할 수 있습니다(../api/pipelines/stable_diffusion/pix2pix_zero#usage-example).
|
||||
|
||||
</Tip>
|
||||
|
||||
위에서 언급했듯이 Pix2Pix Zero에는 특정 개념으로 세대를 유도하기 위해 (UNet, VAE 또는 텍스트 인코더가 아닌) latents을 최적화하는 기능이 포함되어 있습니다.즉, 전체 파이프라인에 표준 [StableDiffusionPipeline](../api/pipelines/stable_diffusion/text2img)보다 더 많은 메모리가 필요할 수 있습니다.
|
||||
|
||||
사용 방법에 대한 자세한 내용은 [여기](../api/pipelines/stable_diffusion/pix2pix_zero)를 참조하세요.
|
||||
|
||||
## Attend and Excite
|
||||
|
||||
[Paper](https://arxiv.org/abs/2301.13826)
|
||||
|
||||
[Attend and Excite](../api/pipelines/stable_diffusion/attend_and_excite)를 사용하면 프롬프트의 피사체가 최종 이미지에 충실하게 표현되도록 할 수 있습니다.
|
||||
|
||||
이미지에 존재해야 하는 프롬프트의 피사체에 해당하는 일련의 토큰 인덱스가 입력으로 제공됩니다. 노이즈 제거 중에 각 토큰 인덱스는 이미지의 최소 한 패치 이상에 대해 최소 주의 임계값을 갖도록 보장됩니다. 모든 피사체 토큰에 대해 주의 임계값이 통과될 때까지 노이즈 제거 프로세스 중에 중간 잠복기가 반복적으로 최적화되어 가장 소홀히 취급되는 피사체 토큰의 주의력을 강화합니다.
|
||||
|
||||
Pix2Pix Zero와 마찬가지로 Attend and Excite 역시 파이프라인에 미니 최적화 루프(사전 학습된 가중치를 그대로 둔 채)가 포함되며, 일반적인 'StableDiffusionPipeline'보다 더 많은 메모리가 필요할 수 있습니다.
|
||||
|
||||
사용 방법에 대한 자세한 내용은 [여기](../api/pipelines/stable_diffusion/attend_and_excite)를 참조하세요.
|
||||
|
||||
## Semantic Guidance (SEGA)
|
||||
|
||||
[Paper](https://arxiv.org/abs/2301.12247)
|
||||
|
||||
의미유도(SEGA)를 사용하면 이미지에서 하나 이상의 컨셉을 적용하거나 제거할 수 있습니다. 컨셉의 강도도 조절할 수 있습니다. 즉, 스마일 컨셉을 사용하여 인물 사진의 스마일을 점진적으로 늘리거나 줄일 수 있습니다.
|
||||
|
||||
분류기 무료 안내(classifier free guidance)가 빈 프롬프트 입력을 통해 안내를 제공하는 방식과 유사하게, SEGA는 개념 프롬프트에 대한 안내를 제공합니다. 이러한 개념 프롬프트는 여러 개를 동시에 적용할 수 있습니다. 각 개념 프롬프트는 안내가 긍정적으로 적용되는지 또는 부정적으로 적용되는지에 따라 해당 개념을 추가하거나 제거할 수 있습니다.
|
||||
|
||||
Pix2Pix Zero 또는 Attend and Excite와 달리 SEGA는 명시적인 그라데이션 기반 최적화를 수행하는 대신 확산 프로세스와 직접 상호 작용합니다.
|
||||
|
||||
사용 방법에 대한 자세한 내용은 [여기](../api/pipelines/semantic_stable_diffusion)를 참조하세요.
|
||||
|
||||
## Self-attention Guidance (SAG)
|
||||
|
||||
[Paper](https://arxiv.org/abs/2210.00939)
|
||||
|
||||
[자기 주의 안내](../api/pipelines/stable_diffusion/self_attention_guidance)는 이미지의 전반적인 품질을 개선합니다.
|
||||
|
||||
SAG는 고빈도 세부 정보를 기반으로 하지 않은 예측에서 완전히 조건화된 이미지에 이르기까지 가이드를 제공합니다. 고빈도 디테일은 UNet 자기 주의 맵에서 추출됩니다.
|
||||
|
||||
사용 방법에 대한 자세한 내용은 [여기](../api/pipelines/stable_diffusion/self_attention_guidance)를 참조하세요.
|
||||
|
||||
## Depth2Image
|
||||
|
||||
[Project](https://huggingface.co/stabilityai/stable-diffusion-2-depth)
|
||||
|
||||
[Depth2Image](../pipelines/stable_diffusion_2#depthtoimage)는 텍스트 안내 이미지 변화에 대한 시맨틱을 더 잘 보존하도록 안정적 확산에서 미세 조정되었습니다.
|
||||
|
||||
원본 이미지의 단안(monocular) 깊이 추정치를 조건으로 합니다.
|
||||
|
||||
사용 방법에 대한 자세한 내용은 [여기](../api/pipelines/stable_diffusion_2#depthtoimage)를 참조하세요.
|
||||
|
||||
<Tip>
|
||||
|
||||
InstructPix2Pix와 Pix2Pix Zero와 같은 방법의 중요한 차이점은 전자의 경우
|
||||
는 사전 학습된 가중치를 미세 조정하는 반면, 후자는 그렇지 않다는 것입니다. 즉, 다음을 수행할 수 있습니다.
|
||||
사용 가능한 모든 안정적 확산 모델에 Pix2Pix Zero를 적용할 수 있습니다.
|
||||
|
||||
</Tip>
|
||||
|
||||
## MultiDiffusion Panorama
|
||||
|
||||
[Paper](https://arxiv.org/abs/2302.08113)
|
||||
|
||||
MultiDiffusion은 사전 학습된 diffusion model을 통해 새로운 생성 프로세스를 정의합니다. 이 프로세스는 고품질의 다양한 이미지를 생성하는 데 쉽게 적용할 수 있는 여러 diffusion 생성 방법을 하나로 묶습니다. 결과는 원하는 종횡비(예: 파노라마) 및 타이트한 분할 마스크에서 바운딩 박스에 이르는 공간 안내 신호와 같은 사용자가 제공한 제어를 준수합니다.
|
||||
[MultiDiffusion 파노라마](../api/pipelines/stable_diffusion/panorama)를 사용하면 임의의 종횡비(예: 파노라마)로 고품질 이미지를 생성할 수 있습니다.
|
||||
|
||||
파노라마 이미지를 생성하는 데 사용하는 방법에 대한 자세한 내용은 [여기](../api/pipelines/stable_diffusion/panorama)를 참조하세요.
|
||||
|
||||
## 나만의 모델 파인튜닝
|
||||
|
||||
사전 학습된 모델 외에도 Diffusers는 사용자가 제공한 데이터에 대해 모델을 파인튜닝할 수 있는 학습 스크립트가 있습니다.
|
||||
|
||||
## DreamBooth
|
||||
|
||||
[DreamBooth](../training/dreambooth)는 모델을 파인튜닝하여 새로운 주제에 대해 가르칩니다. 즉, 한 사람의 사진 몇 장을 사용하여 다양한 스타일로 그 사람의 이미지를 생성할 수 있습니다.
|
||||
|
||||
사용 방법에 대한 자세한 내용은 [여기](../training/dreambooth)를 참조하세요.
|
||||
|
||||
## Textual Inversion
|
||||
|
||||
[Textual Inversion](../training/text_inversion)은 모델을 파인튜닝하여 새로운 개념에 대해 학습시킵니다. 즉, 특정 스타일의 아트웍 사진 몇 장을 사용하여 해당 스타일의 이미지를 생성할 수 있습니다.
|
||||
|
||||
사용 방법에 대한 자세한 내용은 [여기](../training/text_inversion)를 참조하세요.
|
||||
|
||||
## ControlNet
|
||||
|
||||
[Paper](https://arxiv.org/abs/2302.05543)
|
||||
|
||||
[ControlNet](../api/pipelines/stable_diffusion/controlnet)은 추가 조건을 추가하는 보조 네트워크입니다.
|
||||
가장자리 감지, 낙서, 깊이 맵, 의미적 세그먼트와 같은 다양한 조건에 대해 훈련된 8개의 표준 사전 훈련된 ControlNet이 있습니다,
|
||||
깊이 맵, 시맨틱 세그먼테이션과 같은 다양한 조건으로 훈련된 8개의 표준 제어망이 있습니다.
|
||||
|
||||
사용 방법에 대한 자세한 내용은 [여기](../api/pipelines/stable_diffusion/controlnet)를 참조하세요.
|
||||
|
||||
## Prompt Weighting
|
||||
|
||||
프롬프트 가중치는 텍스트의 특정 부분에 더 많은 관심 가중치를 부여하는 간단한 기법입니다.
|
||||
입력에 가중치를 부여하는 간단한 기법입니다.
|
||||
|
||||
자세한 설명과 예시는 [여기](../using-diffusers/weighted_prompts)를 참조하세요.
|
||||
|
||||
## Custom Diffusion
|
||||
|
||||
[Custom Diffusion](../training/custom_diffusion)은 사전 학습된 text-to-image 간 확산 모델의 교차 관심도 맵만 미세 조정합니다.
|
||||
또한 textual inversion을 추가로 수행할 수 있습니다. 설계상 다중 개념 훈련을 지원합니다.
|
||||
DreamBooth 및 Textual Inversion 마찬가지로, 사용자 지정 확산은 사전학습된 text-to-image diffusion 모델에 새로운 개념을 학습시켜 관심 있는 개념과 관련된 출력을 생성하는 데에도 사용됩니다.
|
||||
|
||||
자세한 설명은 [공식 문서](../training/custom_diffusion)를 참조하세요.
|
||||
|
||||
## Model Editing
|
||||
|
||||
[Paper](https://arxiv.org/abs/2303.08084)
|
||||
|
||||
[텍스트-이미지 모델 편집 파이프라인](../api/pipelines/model_editing)을 사용하면 사전학습된 text-to-image diffusion 모델이 입력 프롬프트에 있는 피사체에 대해 내릴 수 있는 잘못된 암시적 가정을 완화하는 데 도움이 됩니다.
|
||||
예를 들어, 안정적 확산에 "A pack of roses"에 대한 이미지를 생성하라는 메시지를 표시하면 생성된 이미지의 장미는 빨간색일 가능성이 높습니다. 이 파이프라인은 이러한 가정을 변경하는 데 도움이 됩니다.
|
||||
|
||||
자세한 설명은 [공식 문서](../api/pipelines/model_editing)를 참조하세요.
|
||||
|
||||
## DiffEdit
|
||||
|
||||
[Paper](https://arxiv.org/abs/2210.11427)
|
||||
|
||||
[DiffEdit](../api/pipelines/diffedit)를 사용하면 원본 입력 이미지를 최대한 보존하면서 입력 프롬프트와 함께 입력 이미지의 의미론적 편집이 가능합니다.
|
||||
|
||||
|
||||
자세한 설명은 [공식 문서](../api/pipelines/diffedit)를 참조하세요.
|
||||
|
||||
## T2I-Adapter
|
||||
|
||||
[Paper](https://arxiv.org/abs/2302.08453)
|
||||
|
||||
[T2I-어댑터](../api/pipelines/stable_diffusion/adapter)는 추가적인 조건을 추가하는 auxiliary 네트워크입니다.
|
||||
가장자리 감지, 스케치, depth maps, semantic segmentations와 같은 다양한 조건에 대해 훈련된 8개의 표준 사전훈련된 adapter가 있습니다,
|
||||
|
||||
[공식 문서](api/pipelines/stable_diffusion/adapter)에서 사용 방법에 대한 정보를 참조하세요.
|
||||
@@ -0,0 +1,275 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# 커뮤니티 파이프라인
|
||||
|
||||
> **커뮤니티 파이프라인에 대한 자세한 내용은 [이 이슈](https://github.com/huggingface/diffusers/issues/841)를 참조하세요.
|
||||
|
||||
**커뮤니티** 예제는 커뮤니티에서 추가한 추론 및 훈련 예제로 구성되어 있습니다.
|
||||
다음 표를 참조하여 모든 커뮤니티 예제에 대한 개요를 확인하시기 바랍니다. **코드 예제**를 클릭하면 복사하여 붙여넣기할 수 있는 코드 예제를 확인할 수 있습니다.
|
||||
커뮤니티가 예상대로 작동하지 않는 경우 이슈를 개설하고 작성자에게 핑을 보내주세요.
|
||||
|
||||
| 예 | 설명 | 코드 예제 | 콜랩 |저자 |
|
||||
|:---------------------------------------|:------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|:---------------------------------------------------------------------------------|:-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|-----------------------------------------------------------:|
|
||||
| CLIP Guided Stable Diffusion | CLIP 가이드 기반의 Stable Diffusion으로 텍스트에서 이미지로 생성하기 | [CLIP Guided Stable Diffusion](#clip-guided-stable-diffusion) | [](https://colab.research.google.com/github/huggingface/notebooks/blob/main/diffusers/CLIP_Guided_Stable_diffusion_with_diffusers.ipynb) | [Suraj Patil](https://github.com/patil-suraj/) |
|
||||
| One Step U-Net (Dummy) | 커뮤니티 파이프라인을 어떻게 사용해야 하는지에 대한 예시(참고 https://github.com/huggingface/diffusers/issues/841) | [One Step U-Net](#one-step-unet) | - | [Patrick von Platen](https://github.com/patrickvonplaten/) |
|
||||
| Stable Diffusion Interpolation | 서로 다른 프롬프트/시드 간 Stable Diffusion의 latent space 보간 | [Stable Diffusion Interpolation](#stable-diffusion-interpolation) | - | [Nate Raw](https://github.com/nateraw/) |
|
||||
| Stable Diffusion Mega | 모든 기능을 갖춘 **하나의** Stable Diffusion 파이프라인 [Text2Image](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion.py), [Image2Image](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion_img2img.py) and [Inpainting](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion_inpaint.py) | [Stable Diffusion Mega](#stable-diffusion-mega) | - | [Patrick von Platen](https://github.com/patrickvonplaten/) |
|
||||
| Long Prompt Weighting Stable Diffusion | 토큰 길이 제한이 없고 프롬프트에서 파싱 가중치 지원을 하는 **하나의** Stable Diffusion 파이프라인, | [Long Prompt Weighting Stable Diffusion](#long-prompt-weighting-stable-diffusion) |- | [SkyTNT](https://github.com/SkyTNT) |
|
||||
| Speech to Image | 자동 음성 인식을 사용하여 텍스트를 작성하고 Stable Diffusion을 사용하여 이미지를 생성합니다. | [Speech to Image](#speech-to-image) | - | [Mikail Duzenli](https://github.com/MikailINTech) |
|
||||
|
||||
커스텀 파이프라인을 불러오려면 `diffusers/examples/community`에 있는 파일 중 하나로서 `custom_pipeline` 인수를 `DiffusionPipeline`에 전달하기만 하면 됩니다. 자신만의 파이프라인이 있는 PR을 보내주시면 빠르게 병합해드리겠습니다.
|
||||
```py
|
||||
pipe = DiffusionPipeline.from_pretrained(
|
||||
"CompVis/stable-diffusion-v1-4", custom_pipeline="filename_in_the_community_folder"
|
||||
)
|
||||
```
|
||||
|
||||
## 사용 예시
|
||||
|
||||
### CLIP 가이드 기반의 Stable Diffusion
|
||||
|
||||
모든 노이즈 제거 단계에서 추가 CLIP 모델을 통해 Stable Diffusion을 가이드함으로써 CLIP 모델 기반의 Stable Diffusion은 보다 더 사실적인 이미지를 생성을 할 수 있습니다.
|
||||
|
||||
다음 코드는 약 12GB의 GPU RAM이 필요합니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
from transformers import CLIPImageProcessor, CLIPModel
|
||||
import torch
|
||||
|
||||
|
||||
feature_extractor = CLIPImageProcessor.from_pretrained("laion/CLIP-ViT-B-32-laion2B-s34B-b79K")
|
||||
clip_model = CLIPModel.from_pretrained("laion/CLIP-ViT-B-32-laion2B-s34B-b79K", torch_dtype=torch.float16)
|
||||
|
||||
|
||||
guided_pipeline = DiffusionPipeline.from_pretrained(
|
||||
"CompVis/stable-diffusion-v1-4",
|
||||
custom_pipeline="clip_guided_stable_diffusion",
|
||||
clip_model=clip_model,
|
||||
feature_extractor=feature_extractor,
|
||||
torch_dtype=torch.float16,
|
||||
)
|
||||
guided_pipeline.enable_attention_slicing()
|
||||
guided_pipeline = guided_pipeline.to("cuda")
|
||||
|
||||
prompt = "fantasy book cover, full moon, fantasy forest landscape, golden vector elements, fantasy magic, dark light night, intricate, elegant, sharp focus, illustration, highly detailed, digital painting, concept art, matte, art by WLOP and Artgerm and Albert Bierstadt, masterpiece"
|
||||
|
||||
generator = torch.Generator(device="cuda").manual_seed(0)
|
||||
images = []
|
||||
for i in range(4):
|
||||
image = guided_pipeline(
|
||||
prompt,
|
||||
num_inference_steps=50,
|
||||
guidance_scale=7.5,
|
||||
clip_guidance_scale=100,
|
||||
num_cutouts=4,
|
||||
use_cutouts=False,
|
||||
generator=generator,
|
||||
).images[0]
|
||||
images.append(image)
|
||||
|
||||
# 이미지 로컬에 저장하기
|
||||
for i, img in enumerate(images):
|
||||
img.save(f"./clip_guided_sd/image_{i}.png")
|
||||
```
|
||||
|
||||
이미지` 목록에는 로컬에 저장하거나 구글 콜랩에 직접 표시할 수 있는 PIL 이미지 목록이 포함되어 있습니다. 생성된 이미지는 기본적으로 안정적인 확산을 사용하는 것보다 품질이 높은 경향이 있습니다. 예를 들어 위의 스크립트는 다음과 같은 이미지를 생성합니다:
|
||||
|
||||
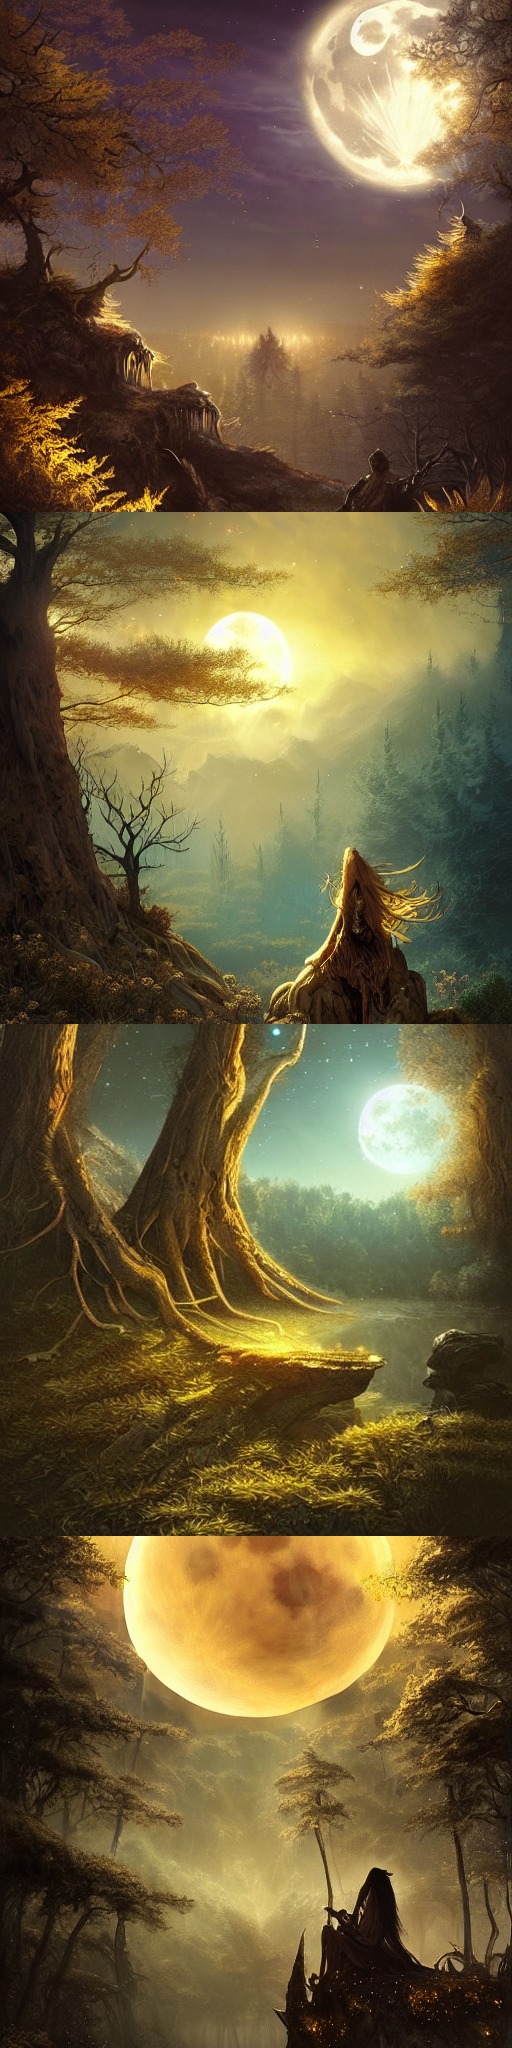.
|
||||
|
||||
### One Step Unet
|
||||
|
||||
예시 "one-step-unet"는 다음과 같이 실행할 수 있습니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
pipe = DiffusionPipeline.from_pretrained("google/ddpm-cifar10-32", custom_pipeline="one_step_unet")
|
||||
pipe()
|
||||
```
|
||||
|
||||
**참고**: 이 커뮤니티 파이프라인은 기능으로 유용하지 않으며 커뮤니티 파이프라인을 추가할 수 있는 방법의 예시일 뿐입니다(https://github.com/huggingface/diffusers/issues/841 참조).
|
||||
|
||||
### Stable Diffusion Interpolation
|
||||
|
||||
다음 코드는 최소 8GB VRAM의 GPU에서 실행할 수 있으며 약 5분 정도 소요됩니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
import torch
|
||||
|
||||
pipe = DiffusionPipeline.from_pretrained(
|
||||
"CompVis/stable-diffusion-v1-4",
|
||||
torch_dtype=torch.float16,
|
||||
safety_checker=None, # Very important for videos...lots of false positives while interpolating
|
||||
custom_pipeline="interpolate_stable_diffusion",
|
||||
).to("cuda")
|
||||
pipe.enable_attention_slicing()
|
||||
|
||||
frame_filepaths = pipe.walk(
|
||||
prompts=["a dog", "a cat", "a horse"],
|
||||
seeds=[42, 1337, 1234],
|
||||
num_interpolation_steps=16,
|
||||
output_dir="./dreams",
|
||||
batch_size=4,
|
||||
height=512,
|
||||
width=512,
|
||||
guidance_scale=8.5,
|
||||
num_inference_steps=50,
|
||||
)
|
||||
```
|
||||
|
||||
walk(...)` 함수의 출력은 `output_dir`에 정의된 대로 폴더에 저장된 이미지 목록을 반환합니다. 이 이미지를 사용하여 안정적으로 확산되는 동영상을 만들 수 있습니다.
|
||||
|
||||
> 안정된 확산을 이용한 동영상 제작 방법과 더 많은 기능에 대한 자세한 내용은 https://github.com/nateraw/stable-diffusion-videos 에서 확인하시기 바랍니다.
|
||||
|
||||
### Stable Diffusion Mega
|
||||
|
||||
The Stable Diffusion Mega 파이프라인을 사용하면 Stable Diffusion 파이프라인의 주요 사용 사례를 단일 클래스에서 사용할 수 있습니다.
|
||||
```python
|
||||
#!/usr/bin/env python3
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
import PIL
|
||||
import requests
|
||||
from io import BytesIO
|
||||
import torch
|
||||
|
||||
|
||||
def download_image(url):
|
||||
response = requests.get(url)
|
||||
return PIL.Image.open(BytesIO(response.content)).convert("RGB")
|
||||
|
||||
|
||||
pipe = DiffusionPipeline.from_pretrained(
|
||||
"CompVis/stable-diffusion-v1-4",
|
||||
custom_pipeline="stable_diffusion_mega",
|
||||
torch_dtype=torch.float16,
|
||||
)
|
||||
pipe.to("cuda")
|
||||
pipe.enable_attention_slicing()
|
||||
|
||||
|
||||
### Text-to-Image
|
||||
|
||||
images = pipe.text2img("An astronaut riding a horse").images
|
||||
|
||||
### Image-to-Image
|
||||
|
||||
init_image = download_image(
|
||||
"https://raw.githubusercontent.com/CompVis/stable-diffusion/main/assets/stable-samples/img2img/sketch-mountains-input.jpg"
|
||||
)
|
||||
|
||||
prompt = "A fantasy landscape, trending on artstation"
|
||||
|
||||
images = pipe.img2img(prompt=prompt, image=init_image, strength=0.75, guidance_scale=7.5).images
|
||||
|
||||
### Inpainting
|
||||
|
||||
img_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo.png"
|
||||
mask_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png"
|
||||
init_image = download_image(img_url).resize((512, 512))
|
||||
mask_image = download_image(mask_url).resize((512, 512))
|
||||
|
||||
prompt = "a cat sitting on a bench"
|
||||
images = pipe.inpaint(prompt=prompt, image=init_image, mask_image=mask_image, strength=0.75).images
|
||||
```
|
||||
|
||||
위에 표시된 것처럼 하나의 파이프라인에서 '텍스트-이미지 변환', '이미지-이미지 변환', '인페인팅'을 모두 실행할 수 있습니다.
|
||||
|
||||
### Long Prompt Weighting Stable Diffusion
|
||||
|
||||
파이프라인을 사용하면 77개의 토큰 길이 제한 없이 프롬프트를 입력할 수 있습니다. 또한 "()"를 사용하여 단어 가중치를 높이거나 "[]"를 사용하여 단어 가중치를 낮출 수 있습니다.
|
||||
또한 파이프라인을 사용하면 단일 클래스에서 Stable Diffusion 파이프라인의 주요 사용 사례를 사용할 수 있습니다.
|
||||
|
||||
#### pytorch
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
import torch
|
||||
|
||||
pipe = DiffusionPipeline.from_pretrained(
|
||||
"hakurei/waifu-diffusion", custom_pipeline="lpw_stable_diffusion", torch_dtype=torch.float16
|
||||
)
|
||||
pipe = pipe.to("cuda")
|
||||
|
||||
prompt = "best_quality (1girl:1.3) bow bride brown_hair closed_mouth frilled_bow frilled_hair_tubes frills (full_body:1.3) fox_ear hair_bow hair_tubes happy hood japanese_clothes kimono long_sleeves red_bow smile solo tabi uchikake white_kimono wide_sleeves cherry_blossoms"
|
||||
neg_prompt = "lowres, bad_anatomy, error_body, error_hair, error_arm, error_hands, bad_hands, error_fingers, bad_fingers, missing_fingers, error_legs, bad_legs, multiple_legs, missing_legs, error_lighting, error_shadow, error_reflection, text, error, extra_digit, fewer_digits, cropped, worst_quality, low_quality, normal_quality, jpeg_artifacts, signature, watermark, username, blurry"
|
||||
|
||||
pipe.text2img(prompt, negative_prompt=neg_prompt, width=512, height=512, max_embeddings_multiples=3).images[0]
|
||||
```
|
||||
|
||||
#### onnxruntime
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
import torch
|
||||
|
||||
pipe = DiffusionPipeline.from_pretrained(
|
||||
"CompVis/stable-diffusion-v1-4",
|
||||
custom_pipeline="lpw_stable_diffusion_onnx",
|
||||
revision="onnx",
|
||||
provider="CUDAExecutionProvider",
|
||||
)
|
||||
|
||||
prompt = "a photo of an astronaut riding a horse on mars, best quality"
|
||||
neg_prompt = "lowres, bad anatomy, error body, error hair, error arm, error hands, bad hands, error fingers, bad fingers, missing fingers, error legs, bad legs, multiple legs, missing legs, error lighting, error shadow, error reflection, text, error, extra digit, fewer digits, cropped, worst quality, low quality, normal quality, jpeg artifacts, signature, watermark, username, blurry"
|
||||
|
||||
pipe.text2img(prompt, negative_prompt=neg_prompt, width=512, height=512, max_embeddings_multiples=3).images[0]
|
||||
```
|
||||
|
||||
토큰 인덱스 시퀀스 길이가 이 모델에 지정된 최대 시퀀스 길이보다 길면(*** > 77). 이 시퀀스를 모델에서 실행하면 인덱싱 오류가 발생합니다`. 정상적인 현상이니 걱정하지 마세요.
|
||||
### Speech to Image
|
||||
|
||||
다음 코드는 사전학습된 OpenAI whisper-small과 Stable Diffusion을 사용하여 오디오 샘플에서 이미지를 생성할 수 있습니다.
|
||||
```Python
|
||||
import torch
|
||||
|
||||
import matplotlib.pyplot as plt
|
||||
from datasets import load_dataset
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
from transformers import (
|
||||
WhisperForConditionalGeneration,
|
||||
WhisperProcessor,
|
||||
)
|
||||
|
||||
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
|
||||
ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
|
||||
|
||||
audio_sample = ds[3]
|
||||
|
||||
text = audio_sample["text"].lower()
|
||||
speech_data = audio_sample["audio"]["array"]
|
||||
|
||||
model = WhisperForConditionalGeneration.from_pretrained("openai/whisper-small").to(device)
|
||||
processor = WhisperProcessor.from_pretrained("openai/whisper-small")
|
||||
|
||||
diffuser_pipeline = DiffusionPipeline.from_pretrained(
|
||||
"CompVis/stable-diffusion-v1-4",
|
||||
custom_pipeline="speech_to_image_diffusion",
|
||||
speech_model=model,
|
||||
speech_processor=processor,
|
||||
|
||||
torch_dtype=torch.float16,
|
||||
)
|
||||
|
||||
diffuser_pipeline.enable_attention_slicing()
|
||||
diffuser_pipeline = diffuser_pipeline.to(device)
|
||||
|
||||
output = diffuser_pipeline(speech_data)
|
||||
plt.imshow(output.images[0])
|
||||
```
|
||||
위 예시는 다음의 결과 이미지를 보입니다.
|
||||
|
||||
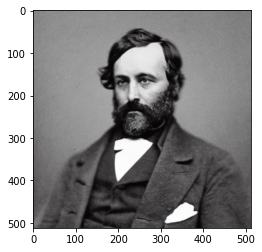
|
||||
@@ -0,0 +1,56 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# 커스텀 파이프라인 불러오기
|
||||
|
||||
[[open-in-colab]]
|
||||
|
||||
커뮤니티 파이프라인은 논문에 명시된 원래의 구현체와 다른 형태로 구현된 모든 [`DiffusionPipeline`] 클래스를 의미합니다. (예를 들어, [`StableDiffusionControlNetPipeline`]는 ["Text-to-Image Generation with ControlNet Conditioning"](https://arxiv.org/abs/2302.05543) 해당) 이들은 추가 기능을 제공하거나 파이프라인의 원래 구현을 확장합니다.
|
||||
|
||||
[Speech to Image](https://github.com/huggingface/diffusers/tree/main/examples/community#speech-to-image) 또는 [Composable Stable Diffusion](https://github.com/huggingface/diffusers/tree/main/examples/community#composable-stable-diffusion) 과 같은 멋진 커뮤니티 파이프라인이 많이 있으며 [여기에서](https://github.com/huggingface/diffusers/tree/main/examples/community) 모든 공식 커뮤니티 파이프라인을 찾을 수 있습니다.
|
||||
|
||||
허브에서 커뮤니티 파이프라인을 로드하려면, 커뮤니티 파이프라인의 리포지토리 ID와 (파이프라인 가중치 및 구성 요소를 로드하려는) 모델의 리포지토리 ID를 인자로 전달해야 합니다. 예를 들어, 아래 예시에서는 `hf-internal-testing/diffusers-dummy-pipeline`에서 더미 파이프라인을 불러오고, `google/ddpm-cifar10-32`에서 파이프라인의 가중치와 컴포넌트들을 로드합니다.
|
||||
|
||||
<Tip warning={true}>
|
||||
|
||||
🔒 허깅 페이스 허브에서 커뮤니티 파이프라인을 불러오는 것은 곧 해당 코드가 안전하다고 신뢰하는 것입니다. 코드를 자동으로 불러오고 실행하기 앞서 반드시 온라인으로 해당 코드의 신뢰성을 검사하세요!
|
||||
|
||||
</Tip>
|
||||
|
||||
```py
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
pipeline = DiffusionPipeline.from_pretrained(
|
||||
"google/ddpm-cifar10-32", custom_pipeline="hf-internal-testing/diffusers-dummy-pipeline"
|
||||
)
|
||||
```
|
||||
|
||||
공식 커뮤니티 파이프라인을 불러오는 것은 비슷하지만, 공식 리포지토리 ID에서 가중치를 불러오는 것과 더불어 해당 파이프라인 내의 컴포넌트를 직접 지정하는 것 역시 가능합니다. 아래 예제를 보면 커뮤니티 [CLIP Guided Stable Diffusion](https://github.com/huggingface/diffusers/tree/main/examples/community#clip-guided-stable-diffusion) 파이프라인을 로드할 때, 해당 파이프라인에서 사용할 `clip_model` 컴포넌트와 `feature_extractor` 컴포넌트를 직접 설정하는 것을 확인할 수 있습니다.
|
||||
|
||||
```py
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
from transformers import CLIPImageProcessor, CLIPModel
|
||||
|
||||
clip_model_id = "laion/CLIP-ViT-B-32-laion2B-s34B-b79K"
|
||||
|
||||
feature_extractor = CLIPImageProcessor.from_pretrained(clip_model_id)
|
||||
clip_model = CLIPModel.from_pretrained(clip_model_id)
|
||||
|
||||
pipeline = DiffusionPipeline.from_pretrained(
|
||||
"runwayml/stable-diffusion-v1-5",
|
||||
custom_pipeline="clip_guided_stable_diffusion",
|
||||
clip_model=clip_model,
|
||||
feature_extractor=feature_extractor,
|
||||
)
|
||||
```
|
||||
|
||||
커뮤니티 파이프라인에 대한 자세한 내용은 [커뮤니티 파이프라인](https://github.com/huggingface/diffusers/blob/main/docs/source/en/using-diffusers/custom_pipeline_examples) 가이드를 살펴보세요. 커뮤니티 파이프라인 등록에 관심이 있는 경우 [커뮤니티 파이프라인에 기여하는 방법](https://github.com/huggingface/diffusers/blob/main/docs/source/en/using-diffusers/contribute_pipeline)에 대한 가이드를 확인하세요 !
|
||||
@@ -0,0 +1,57 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# Text-guided depth-to-image 생성
|
||||
|
||||
[[open-in-colab]]
|
||||
|
||||
[`StableDiffusionDepth2ImgPipeline`]을 사용하면 텍스트 프롬프트와 초기 이미지를 전달하여 새 이미지의 생성을 조절할 수 있습니다. 또한 이미지 구조를 보존하기 위해 `depth_map`을 전달할 수도 있습니다. `depth_map`이 제공되지 않으면 파이프라인은 통합된 [depth-estimation model](https://github.com/isl-org/MiDaS)을 통해 자동으로 깊이를 예측합니다.
|
||||
|
||||
|
||||
먼저 [`StableDiffusionDepth2ImgPipeline`]의 인스턴스를 생성합니다:
|
||||
|
||||
```python
|
||||
import torch
|
||||
import requests
|
||||
from PIL import Image
|
||||
|
||||
from MuseVdiffusers import StableDiffusionDepth2ImgPipeline
|
||||
|
||||
pipe = StableDiffusionDepth2ImgPipeline.from_pretrained(
|
||||
"stabilityai/stable-diffusion-2-depth",
|
||||
torch_dtype=torch.float16,
|
||||
).to("cuda")
|
||||
```
|
||||
|
||||
이제 프롬프트를 파이프라인에 전달합니다. 특정 단어가 이미지 생성을 가이드 하는것을 방지하기 위해 `negative_prompt`를 전달할 수도 있습니다:
|
||||
|
||||
```python
|
||||
url = "http://images.cocodataset.org/val2017/000000039769.jpg"
|
||||
init_image = Image.open(requests.get(url, stream=True).raw)
|
||||
prompt = "two tigers"
|
||||
n_prompt = "bad, deformed, ugly, bad anatomy"
|
||||
image = pipe(prompt=prompt, image=init_image, negative_prompt=n_prompt, strength=0.7).images[0]
|
||||
image
|
||||
```
|
||||
|
||||
| Input | Output |
|
||||
|---------------------------------------------------------------------------------|---------------------------------------------------------------------------------------------------------------------------------------|
|
||||
| <img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/coco-cats.png" width="500"/> | <img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/depth2img-tigers.png" width="500"/> |
|
||||
|
||||
아래의 Spaces를 가지고 놀며 depth map이 있는 이미지와 없는 이미지의 차이가 있는지 확인해 보세요!
|
||||
|
||||
<iframe
|
||||
src="https://radames-stable-diffusion-depth2img.hf.space"
|
||||
frameborder="0"
|
||||
width="850"
|
||||
height="500"
|
||||
></iframe>
|
||||
@@ -0,0 +1,100 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# 텍스트 기반 image-to-image 생성
|
||||
|
||||
[[open-in-colab]]
|
||||
|
||||
[`StableDiffusionImg2ImgPipeline`]을 사용하면 텍스트 프롬프트와 시작 이미지를 전달하여 새 이미지 생성의 조건을 지정할 수 있습니다.
|
||||
|
||||
시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
|
||||
|
||||
```bash
|
||||
!pip install diffusers transformers ftfy accelerate
|
||||
```
|
||||
|
||||
[`nitrosocke/Ghibli-Diffusion`](https://huggingface.co/nitrosocke/Ghibli-Diffusion)과 같은 사전학습된 stable diffusion 모델로 [`StableDiffusionImg2ImgPipeline`]을 생성하여 시작하세요.
|
||||
|
||||
|
||||
```python
|
||||
import torch
|
||||
import requests
|
||||
from PIL import Image
|
||||
from io import BytesIO
|
||||
from MuseVdiffusers import StableDiffusionImg2ImgPipeline
|
||||
|
||||
device = "cuda"
|
||||
pipe = StableDiffusionImg2ImgPipeline.from_pretrained("nitrosocke/Ghibli-Diffusion", torch_dtype=torch.float16).to(
|
||||
device
|
||||
)
|
||||
```
|
||||
|
||||
초기 이미지를 다운로드하고 사전 처리하여 파이프라인에 전달할 수 있습니다:
|
||||
|
||||
```python
|
||||
url = "https://raw.githubusercontent.com/CompVis/stable-diffusion/main/assets/stable-samples/img2img/sketch-mountains-input.jpg"
|
||||
|
||||
response = requests.get(url)
|
||||
init_image = Image.open(BytesIO(response.content)).convert("RGB")
|
||||
init_image.thumbnail((768, 768))
|
||||
init_image
|
||||
```
|
||||
|
||||
<div class="flex justify-center">
|
||||
<img src="https://huggingface.co/datasets/YiYiXu/test-doc-assets/resolve/main/image_2_image_using_diffusers_cell_8_output_0.jpeg"/>
|
||||
</div>
|
||||
|
||||
<Tip>
|
||||
|
||||
💡 `strength`는 입력 이미지에 추가되는 노이즈의 양을 제어하는 0.0에서 1.0 사이의 값입니다. 1.0에 가까운 값은 다양한 변형을 허용하지만 입력 이미지와 의미적으로 일치하지 않는 이미지를 생성합니다.
|
||||
|
||||
</Tip>
|
||||
|
||||
프롬프트를 정의하고(지브리 스타일(Ghibli-style)에 맞게 조정된 이 체크포인트의 경우 프롬프트 앞에 `ghibli style` 토큰을 붙여야 합니다) 파이프라인을 실행합니다:
|
||||
|
||||
```python
|
||||
prompt = "ghibli style, a fantasy landscape with castles"
|
||||
generator = torch.Generator(device=device).manual_seed(1024)
|
||||
image = pipe(prompt=prompt, image=init_image, strength=0.75, guidance_scale=7.5, generator=generator).images[0]
|
||||
image
|
||||
```
|
||||
|
||||
<div class="flex justify-center">
|
||||
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ghibli-castles.png"/>
|
||||
</div>
|
||||
|
||||
다른 스케줄러로 실험하여 출력에 어떤 영향을 미치는지 확인할 수도 있습니다:
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import LMSDiscreteScheduler
|
||||
|
||||
lms = LMSDiscreteScheduler.from_config(pipe.scheduler.config)
|
||||
pipe.scheduler = lms
|
||||
generator = torch.Generator(device=device).manual_seed(1024)
|
||||
image = pipe(prompt=prompt, image=init_image, strength=0.75, guidance_scale=7.5, generator=generator).images[0]
|
||||
image
|
||||
```
|
||||
|
||||
<div class="flex justify-center">
|
||||
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/lms-ghibli.png"/>
|
||||
</div>
|
||||
|
||||
아래 공백을 확인하고 `strength` 값을 다르게 설정하여 이미지를 생성해 보세요. `strength`를 낮게 설정하면 원본 이미지와 더 유사한 이미지가 생성되는 것을 확인할 수 있습니다.
|
||||
|
||||
자유롭게 스케줄러를 [`LMSDiscreteScheduler`]로 전환하여 출력에 어떤 영향을 미치는지 확인해 보세요.
|
||||
|
||||
<iframe
|
||||
src="https://stevhliu-ghibli-img2img.hf.space"
|
||||
frameborder="0"
|
||||
width="850"
|
||||
height="500"
|
||||
></iframe>
|
||||
@@ -0,0 +1,75 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# Text-guided 이미지 인페인팅(inpainting)
|
||||
|
||||
[[open-in-colab]]
|
||||
|
||||
[`StableDiffusionInpaintPipeline`]은 마스크와 텍스트 프롬프트를 제공하여 이미지의 특정 부분을 편집할 수 있도록 합니다. 이 기능은 인페인팅 작업을 위해 특별히 훈련된 [`runwayml/stable-diffusion-inpainting`](https://huggingface.co/runwayml/stable-diffusion-inpainting)과 같은 Stable Diffusion 버전을 사용합니다.
|
||||
|
||||
먼저 [`StableDiffusionInpaintPipeline`] 인스턴스를 불러옵니다:
|
||||
|
||||
```python
|
||||
import PIL
|
||||
import requests
|
||||
import torch
|
||||
from io import BytesIO
|
||||
|
||||
from MuseVdiffusers import StableDiffusionInpaintPipeline
|
||||
|
||||
pipeline = StableDiffusionInpaintPipeline.from_pretrained(
|
||||
"runwayml/stable-diffusion-inpainting",
|
||||
torch_dtype=torch.float16,
|
||||
)
|
||||
pipeline = pipeline.to("cuda")
|
||||
```
|
||||
|
||||
나중에 교체할 강아지 이미지와 마스크를 다운로드하세요:
|
||||
|
||||
```python
|
||||
def download_image(url):
|
||||
response = requests.get(url)
|
||||
return PIL.Image.open(BytesIO(response.content)).convert("RGB")
|
||||
|
||||
|
||||
img_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo.png"
|
||||
mask_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png"
|
||||
|
||||
init_image = download_image(img_url).resize((512, 512))
|
||||
mask_image = download_image(mask_url).resize((512, 512))
|
||||
```
|
||||
|
||||
이제 마스크를 다른 것으로 교체하라는 프롬프트를 만들 수 있습니다:
|
||||
|
||||
```python
|
||||
prompt = "Face of a yellow cat, high resolution, sitting on a park bench"
|
||||
image = pipe(prompt=prompt, image=init_image, mask_image=mask_image).images[0]
|
||||
```
|
||||
|
||||
`image` | `mask_image` | `prompt` | output |
|
||||
:-------------------------:|:-------------------------:|:-------------------------:|-------------------------:|
|
||||
<img src="https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo.png" alt="drawing" width="250"/> | <img src="https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png" alt="drawing" width="250"/> | ***Face of a yellow cat, high resolution, sitting on a park bench*** | <img src="https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/in_paint/yellow_cat_sitting_on_a_park_bench.png" alt="drawing" width="250"/> |
|
||||
|
||||
<Tip warning={true}>
|
||||
|
||||
이전의 실험적인 인페인팅 구현에서는 품질이 낮은 다른 프로세스를 사용했습니다. 이전 버전과의 호환성을 보장하기 위해 새 모델이 포함되지 않은 사전학습된 파이프라인을 불러오면 이전 인페인팅 방법이 계속 적용됩니다.
|
||||
|
||||
</Tip>
|
||||
|
||||
아래 Space에서 이미지 인페인팅을 직접 해보세요!
|
||||
|
||||
<iframe
|
||||
src="https://runwayml-stable-diffusion-inpainting.hf.space"
|
||||
frameborder="0"
|
||||
width="850"
|
||||
height="500"
|
||||
></iframe>
|
||||
@@ -0,0 +1,442 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
|
||||
|
||||
# 파이프라인, 모델, 스케줄러 불러오기
|
||||
|
||||
기본적으로 diffusion 모델은 다양한 컴포넌트들(모델, 토크나이저, 스케줄러) 간의 복잡한 상호작용을 기반으로 동작합니다. 디퓨저스(Diffusers)는 이러한 diffusion 모델을 보다 쉽고 간편한 API로 제공하는 것을 목표로 설계되었습니다. [`DiffusionPipeline`]은 diffusion 모델이 갖는 복잡성을 하나의 파이프라인 API로 통합하고, 동시에 이를 구성하는 각각의 컴포넌트들을 태스크에 맞춰 유연하게 커스터마이징할 수 있도록 지원하고 있습니다.
|
||||
|
||||
diffusion 모델의 훈련과 추론에 필요한 모든 것은 [`DiffusionPipeline.from_pretrained`] 메서드를 통해 접근할 수 있습니다. (이 말의 의미는 다음 단락에서 보다 자세하게 다뤄보도록 하겠습니다.)
|
||||
|
||||
이 문서에서는 설명할 내용은 다음과 같습니다.
|
||||
|
||||
* 허브를 통해 혹은 로컬로 파이프라인을 불러오는 법
|
||||
|
||||
* 파이프라인에 다른 컴포넌트들을 적용하는 법
|
||||
* 오리지널 체크포인트가 아닌 variant를 불러오는 법 (variant란 기본으로 설정된 `fp32`가 아닌 다른 부동 소수점 타입(예: `fp16`)을 사용하거나 Non-EMA 가중치를 사용하는 체크포인트들을 의미합니다.)
|
||||
* 모델과 스케줄러를 불러오는 법
|
||||
|
||||
|
||||
|
||||
## Diffusion 파이프라인
|
||||
|
||||
<Tip>
|
||||
|
||||
💡 [`DiffusionPipeline`] 클래스가 동작하는 방식에 보다 자세한 내용이 궁금하다면, [DiffusionPipeline explained](#diffusionpipeline에-대해-알아보기) 섹션을 확인해보세요.
|
||||
|
||||
</Tip>
|
||||
|
||||
[`DiffusionPipeline`] 클래스는 diffusion 모델을 [허브](https://huggingface.co/models?library=diffusers)로부터 불러오는 가장 심플하면서 보편적인 방식입니다. [`DiffusionPipeline.from_pretrained`] 메서드는 적합한 파이프라인 클래스를 자동으로 탐지하고, 필요한 구성요소(configuration)와 가중치(weight) 파일들을 다운로드하고 캐싱한 다음, 해당 파이프라인 인스턴스를 반환합니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
repo_id = "runwayml/stable-diffusion-v1-5"
|
||||
pipe = DiffusionPipeline.from_pretrained(repo_id)
|
||||
```
|
||||
|
||||
물론 [`DiffusionPipeline`] 클래스를 사용하지 않고, 명시적으로 직접 해당 파이프라인 클래스를 불러오는 것도 가능합니다. 아래 예시 코드는 위 예시와 동일한 인스턴스를 반환합니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import StableDiffusionPipeline
|
||||
|
||||
repo_id = "runwayml/stable-diffusion-v1-5"
|
||||
pipe = StableDiffusionPipeline.from_pretrained(repo_id)
|
||||
```
|
||||
|
||||
[CompVis/stable-diffusion-v1-4](https://huggingface.co/CompVis/stable-diffusion-v1-4)이나 [runwayml/stable-diffusion-v1-5](https://huggingface.co/runwayml/stable-diffusion-v1-5) 같은 체크포인트들의 경우, 하나 이상의 다양한 태스크에 활용될 수 있습니다. (예를 들어 위의 두 체크포인트의 경우, text-to-image와 image-to-image에 모두 활용될 수 있습니다.) 만약 이러한 체크포인트들을 기본 설정 태스크가 아닌 다른 태스크에 활용하고자 한다면, 해당 태스크에 대응되는 파이프라인(task-specific pipeline)을 사용해야 합니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import StableDiffusionImg2ImgPipeline
|
||||
|
||||
repo_id = "runwayml/stable-diffusion-v1-5"
|
||||
pipe = StableDiffusionImg2ImgPipeline.from_pretrained(repo_id)
|
||||
```
|
||||
|
||||
|
||||
|
||||
### 로컬 파이프라인
|
||||
|
||||
파이프라인을 로컬로 불러오고자 한다면, `git-lfs`를 사용하여 직접 체크포인트를 로컬 디스크에 다운로드 받아야 합니다. 아래의 명령어를 실행하면 `./stable-diffusion-v1-5`란 이름으로 폴더가 로컬디스크에 생성됩니다.
|
||||
|
||||
```bash
|
||||
git lfs install
|
||||
git clone https://huggingface.co/runwayml/stable-diffusion-v1-5
|
||||
```
|
||||
|
||||
그런 다음 해당 로컬 경로를 [`~DiffusionPipeline.from_pretrained`] 메서드에 전달합니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
repo_id = "./stable-diffusion-v1-5"
|
||||
stable_diffusion = DiffusionPipeline.from_pretrained(repo_id)
|
||||
```
|
||||
|
||||
위의 예시코드처럼 만약 `repo_id`가 로컬 패스(local path)라면, [`~DiffusionPipeline.from_pretrained`] 메서드는 이를 자동으로 감지하여 허브에서 파일을 다운로드하지 않습니다. 만약 로컬 디스크에 저장된 파이프라인 체크포인트가 최신 버전이 아닐 경우에도, 최신 버전을 다운로드하지 않고 기존 로컬 디스크에 저장된 체크포인트를 사용한다는 것을 의미합니다.
|
||||
|
||||
|
||||
|
||||
### 파이프라인 내부의 컴포넌트 교체하기
|
||||
|
||||
파이프라인 내부의 컴포넌트들은 호환 가능한 다른 컴포넌트로 교체될 수 있습니다. 이와 같은 컴포넌트 교체가 중요한 이유는 다음과 같습니다.
|
||||
|
||||
- 어떤 스케줄러를 사용할 것인가는 생성속도와 생성품질 간의 트레이드오프를 정의하는 중요한 요소입니다.
|
||||
- diffusion 모델 내부의 컴포넌트들은 일반적으로 각각 독립적으로 훈련되기 때문에, 더 좋은 성능을 보여주는 컴포넌트가 있다면 그걸로 교체하는 식으로 성능을 향상시킬 수 있습니다.
|
||||
- 파인 튜닝 단계에서는 일반적으로 UNet 혹은 텍스트 인코더와 같은 일부 컴포넌트들만 훈련하게 됩니다.
|
||||
|
||||
어떤 스케줄러들이 호환가능한지는 `compatibles` 속성을 통해 확인할 수 있습니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
repo_id = "runwayml/stable-diffusion-v1-5"
|
||||
stable_diffusion = DiffusionPipeline.from_pretrained(repo_id)
|
||||
stable_diffusion.scheduler.compatibles
|
||||
```
|
||||
|
||||
이번에는 [`SchedulerMixin.from_pretrained`] 메서드를 사용해서, 기존 기본 스케줄러였던 [`PNDMScheduler`]를 보다 우수한 성능의 [`EulerDiscreteScheduler`]로 바꿔봅시다. 스케줄러를 로드할 때는 `subfolder` 인자를 통해, 해당 파이프라인의 리포지토리에서 [스케줄러에 관한 하위폴더](https://huggingface.co/runwayml/stable-diffusion-v1-5/tree/main/scheduler)를 명시해주어야 합니다.
|
||||
|
||||
그 다음 새롭게 생성한 [`EulerDiscreteScheduler`] 인스턴스를 [`DiffusionPipeline`]의 `scheduler` 인자에 전달합니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline, EulerDiscreteScheduler, DPMSolverMultistepScheduler
|
||||
|
||||
repo_id = "runwayml/stable-diffusion-v1-5"
|
||||
|
||||
scheduler = EulerDiscreteScheduler.from_pretrained(repo_id, subfolder="scheduler")
|
||||
|
||||
stable_diffusion = DiffusionPipeline.from_pretrained(repo_id, scheduler=scheduler)
|
||||
```
|
||||
|
||||
### 세이프티 체커
|
||||
|
||||
스테이블 diffusion과 같은 diffusion 모델들은 유해한 이미지를 생성할 수도 있습니다. 이를 예방하기 위해 디퓨저스는 생성된 이미지의 유해성을 판단하는 [세이프티 체커(safety checker)](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/safety_checker.py) 기능을 지원하고 있습니다. 만약 세이프티 체커의 사용을 원하지 않는다면, `safety_checker` 인자에 `None`을 전달해주시면 됩니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
repo_id = "runwayml/stable-diffusion-v1-5"
|
||||
stable_diffusion = DiffusionPipeline.from_pretrained(repo_id, safety_checker=None)
|
||||
```
|
||||
|
||||
### 컴포넌트 재사용
|
||||
|
||||
복수의 파이프라인에 동일한 모델이 반복적으로 사용한다면, 굳이 해당 모델의 동일한 가중치를 중복으로 RAM에 불러올 필요는 없을 것입니다. [`~DiffusionPipeline.components`] 속성을 통해 파이프라인 내부의 컴포넌트들을 참조할 수 있는데, 이번 단락에서는 이를 통해 동일한 모델 가중치를 RAM에 중복으로 불러오는 것을 방지하는 법에 대해 알아보겠습니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import StableDiffusionPipeline, StableDiffusionImg2ImgPipeline
|
||||
|
||||
model_id = "runwayml/stable-diffusion-v1-5"
|
||||
stable_diffusion_txt2img = StableDiffusionPipeline.from_pretrained(model_id)
|
||||
|
||||
components = stable_diffusion_txt2img.components
|
||||
```
|
||||
|
||||
그 다음 위 예시 코드에서 선언한 `components` 변수를 다른 파이프라인에 전달함으로써, 모델의 가중치를 중복으로 RAM에 로딩하지 않고, 동일한 컴포넌트를 재사용할 수 있습니다.
|
||||
|
||||
```python
|
||||
stable_diffusion_img2img = StableDiffusionImg2ImgPipeline(**components)
|
||||
```
|
||||
|
||||
물론 각각의 컴포넌트들을 따로 따로 파이프라인에 전달할 수도 있습니다. 예를 들어 `stable_diffusion_txt2img` 파이프라인 안의 컴포넌트들 가운데서 세이프티 체커(`safety_checker`)와 피쳐 익스트랙터(`feature_extractor`)를 제외한 컴포넌트들만 `stable_diffusion_img2img` 파이프라인에서 재사용하는 방식 역시 가능합니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import StableDiffusionPipeline, StableDiffusionImg2ImgPipeline
|
||||
|
||||
model_id = "runwayml/stable-diffusion-v1-5"
|
||||
stable_diffusion_txt2img = StableDiffusionPipeline.from_pretrained(model_id)
|
||||
stable_diffusion_img2img = StableDiffusionImg2ImgPipeline(
|
||||
vae=stable_diffusion_txt2img.vae,
|
||||
text_encoder=stable_diffusion_txt2img.text_encoder,
|
||||
tokenizer=stable_diffusion_txt2img.tokenizer,
|
||||
unet=stable_diffusion_txt2img.unet,
|
||||
scheduler=stable_diffusion_txt2img.scheduler,
|
||||
safety_checker=None,
|
||||
feature_extractor=None,
|
||||
requires_safety_checker=False,
|
||||
)
|
||||
```
|
||||
|
||||
## Checkpoint variants
|
||||
|
||||
Variant란 일반적으로 다음과 같은 체크포인트들을 의미합니다.
|
||||
|
||||
- `torch.float16`과 같이 정밀도는 더 낮지만, 용량 역시 더 작은 부동소수점 타입의 가중치를 사용하는 체크포인트. *(다만 이와 같은 variant의 경우, 추가적인 훈련과 CPU환경에서의 구동이 불가능합니다.)*
|
||||
- Non-EMA 가중치를 사용하는 체크포인트. *(Non-EMA 가중치의 경우, 파인 튜닝 단계에서 사용하는 것이 권장되는데, 추론 단계에선 사용하지 않는 것이 권장됩니다.)*
|
||||
|
||||
<Tip>
|
||||
|
||||
💡 모델 구조는 동일하지만 서로 다른 학습 환경에서 서로 다른 데이터셋으로 학습된 체크포인트들이 있을 경우, 해당 체크포인트들은 variant 단계가 아닌 리포지토리 단계에서 분리되어 관리되어야 합니다. (즉, 해당 체크포인트들은 서로 다른 리포지토리에서 따로 관리되어야 합니다. 예시: [`stable-diffusion-v1-4`], [`stable-diffusion-v1-5`]).
|
||||
|
||||
</Tip>
|
||||
|
||||
| **checkpoint type** | **weight name** | **argument for loading weights** |
|
||||
| ------------------- | ----------------------------------- | -------------------------------- |
|
||||
| original | diffusion_pytorch_model.bin | |
|
||||
| floating point | diffusion_pytorch_model.fp16.bin | `variant`, `torch_dtype` |
|
||||
| non-EMA | diffusion_pytorch_model.non_ema.bin | `variant` |
|
||||
|
||||
variant를 로드할 때 2개의 중요한 argument가 있습니다.
|
||||
|
||||
* `torch_dtype`은 불러올 체크포인트의 부동소수점을 정의합니다. 예를 들어 `torch_dtype=torch.float16`을 명시함으로써 가중치의 부동소수점 타입을 `fl16`으로 변환할 수 있습니다. (만약 따로 설정하지 않을 경우, 기본값으로 `fp32` 타입의 가중치가 로딩됩니다.) 또한 `variant` 인자를 명시하지 않은 채로 체크포인트를 불러온 다음, 해당 체크포인트를 `torch_dtype=torch.float16` 인자를 통해 `fp16` 타입으로 변환하는 것 역시 가능합니다. 이 경우 기본으로 설정된 `fp32` 가중치가 먼저 다운로드되고, 해당 가중치들을 불러온 다음 `fp16` 타입으로 변환하게 됩니다.
|
||||
* `variant` 인자는 리포지토리에서 어떤 variant를 불러올 것인가를 정의합니다. 가령 [`diffusers/stable-diffusion-variants`](https://huggingface.co/diffusers/stable-diffusion-variants/tree/main/unet) 리포지토리로부터 `non_ema` 체크포인트를 불러오고자 한다면, `variant="non_ema"` 인자를 전달해야 합니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
# load fp16 variant
|
||||
stable_diffusion = DiffusionPipeline.from_pretrained(
|
||||
"runwayml/stable-diffusion-v1-5", variant="fp16", torch_dtype=torch.float16
|
||||
)
|
||||
# load non_ema variant
|
||||
stable_diffusion = DiffusionPipeline.from_pretrained("runwayml/stable-diffusion-v1-5", variant="non_ema")
|
||||
```
|
||||
|
||||
다른 부동소수점 타입의 가중치 혹은 non-EMA 가중치를 사용하는 체크포인트를 저장하기 위해서는, [`DiffusionPipeline.save_pretrained`] 메서드를 사용해야 하며, 이 때 `variant` 인자를 명시해줘야 합니다. 원래의 체크포인트와 동일한 폴더에 variant를 저장해야 하며, 이렇게 하면 동일한 폴더에서 오리지널 체크포인트과 variant를 모두 불러올 수 있습니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
# save as fp16 variant
|
||||
stable_diffusion.save_pretrained("runwayml/stable-diffusion-v1-5", variant="fp16")
|
||||
# save as non-ema variant
|
||||
stable_diffusion.save_pretrained("runwayml/stable-diffusion-v1-5", variant="non_ema")
|
||||
```
|
||||
|
||||
만약 variant를 기존 폴더에 저장하지 않을 경우, `variant` 인자를 반드시 명시해야 합니다. 그렇게 하지 않을 경우 원래의 오리지널 체크포인트를 찾을 수 없게 되기 때문에 에러가 발생합니다.
|
||||
|
||||
```python
|
||||
# 👎 this won't work
|
||||
stable_diffusion = DiffusionPipeline.from_pretrained("./stable-diffusion-v1-5", torch_dtype=torch.float16)
|
||||
# 👍 this works
|
||||
stable_diffusion = DiffusionPipeline.from_pretrained(
|
||||
"./stable-diffusion-v1-5", variant="fp16", torch_dtype=torch.float16
|
||||
)
|
||||
```
|
||||
|
||||
### 모델 불러오기
|
||||
|
||||
모델들은 [`ModelMixin.from_pretrained`] 메서드를 통해 불러올 수 있습니다. 해당 메서드는 최신 버전의 모델 가중치 파일과 설정 파일(configurations)을 다운로드하고 캐싱합니다. 만약 이러한 파일들이 최신 버전으로 로컬 캐시에 저장되어 있다면, [`ModelMixin.from_pretrained`]는 굳이 해당 파일들을 다시 다운로드하지 않으며, 그저 캐시에 있는 최신 파일들을 재사용합니다.
|
||||
|
||||
모델은 `subfolder` 인자에 명시된 하위 폴더로부터 로드됩니다. 예를 들어 `runwayml/stable-diffusion-v1-5`의 UNet 모델의 가중치는 [`unet`](https://huggingface.co/runwayml/stable-diffusion-v1-5/tree/main/unet) 폴더에 저장되어 있습니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import UNet2DConditionModel
|
||||
|
||||
repo_id = "runwayml/stable-diffusion-v1-5"
|
||||
model = UNet2DConditionModel.from_pretrained(repo_id, subfolder="unet")
|
||||
```
|
||||
|
||||
혹은 [해당 모델의 리포지토리](https://huggingface.co/google/ddpm-cifar10-32/tree/main)로부터 다이렉트로 가져오는 것 역시 가능합니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import UNet2DModel
|
||||
|
||||
repo_id = "google/ddpm-cifar10-32"
|
||||
model = UNet2DModel.from_pretrained(repo_id)
|
||||
```
|
||||
|
||||
또한 앞서 봤던 `variant` 인자를 명시함으로써, Non-EMA나 `fp16`의 가중치를 가져오는 것 역시 가능합니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import UNet2DConditionModel
|
||||
|
||||
model = UNet2DConditionModel.from_pretrained("runwayml/stable-diffusion-v1-5", subfolder="unet", variant="non-ema")
|
||||
model.save_pretrained("./local-unet", variant="non-ema")
|
||||
```
|
||||
|
||||
### 스케줄러
|
||||
|
||||
스케줄러들은 [`SchedulerMixin.from_pretrained`] 메서드를 통해 불러올 수 있습니다. 모델과 달리 스케줄러는 별도의 가중치를 갖지 않으며, 따라서 당연히 별도의 학습과정을 요구하지 않습니다. 이러한 스케줄러들은 (해당 스케줄러 하위폴더의) configration 파일을 통해 정의됩니다.
|
||||
|
||||
여러개의 스케줄러를 불러온다고 해서 많은 메모리를 소모하는 것은 아니며, 다양한 스케줄러들에 동일한 스케줄러 configration을 적용하는 것 역시 가능합니다. 다음 예시 코드에서 불러오는 스케줄러들은 모두 [`StableDiffusionPipeline`]과 호환되는데, 이는 곧 해당 스케줄러들에 동일한 스케줄러 configration 파일을 적용할 수 있음을 의미합니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import StableDiffusionPipeline
|
||||
from MuseVdiffusers import (
|
||||
DDPMScheduler,
|
||||
DDIMScheduler,
|
||||
PNDMScheduler,
|
||||
LMSDiscreteScheduler,
|
||||
EulerDiscreteScheduler,
|
||||
EulerAncestralDiscreteScheduler,
|
||||
DPMSolverMultistepScheduler,
|
||||
)
|
||||
|
||||
repo_id = "runwayml/stable-diffusion-v1-5"
|
||||
|
||||
ddpm = DDPMScheduler.from_pretrained(repo_id, subfolder="scheduler")
|
||||
ddim = DDIMScheduler.from_pretrained(repo_id, subfolder="scheduler")
|
||||
pndm = PNDMScheduler.from_pretrained(repo_id, subfolder="scheduler")
|
||||
lms = LMSDiscreteScheduler.from_pretrained(repo_id, subfolder="scheduler")
|
||||
euler_anc = EulerAncestralDiscreteScheduler.from_pretrained(repo_id, subfolder="scheduler")
|
||||
euler = EulerDiscreteScheduler.from_pretrained(repo_id, subfolder="scheduler")
|
||||
dpm = DPMSolverMultistepScheduler.from_pretrained(repo_id, subfolder="scheduler")
|
||||
|
||||
# replace `dpm` with any of `ddpm`, `ddim`, `pndm`, `lms`, `euler_anc`, `euler`
|
||||
pipeline = StableDiffusionPipeline.from_pretrained(repo_id, scheduler=dpm)
|
||||
```
|
||||
|
||||
### DiffusionPipeline에 대해 알아보기
|
||||
|
||||
클래스 메서드로서 [`DiffusionPipeline.from_pretrained`]은 2가지를 담당합니다.
|
||||
|
||||
- 첫째로, `from_pretrained` 메서드는 최신 버전의 파이프라인을 다운로드하고, 캐시에 저장합니다. 이미 로컬 캐시에 최신 버전의 파이프라인이 저장되어 있다면, [`DiffusionPipeline.from_pretrained`]은 해당 파일들을 다시 다운로드하지 않고, 로컬 캐시에 저장되어 있는 파이프라인을 불러옵니다.
|
||||
- `model_index.json` 파일을 통해 체크포인트에 대응되는 적합한 파이프라인 클래스로 불러옵니다.
|
||||
|
||||
파이프라인의 폴더 구조는 해당 파이프라인 클래스의 구조와 직접적으로 일치합니다. 예를 들어 [`StableDiffusionPipeline`] 클래스는 [`runwayml/stable-diffusion-v1-5`](https://huggingface.co/runwayml/stable-diffusion-v1-5) 리포지토리와 대응되는 구조를 갖습니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
repo_id = "runwayml/stable-diffusion-v1-5"
|
||||
pipeline = DiffusionPipeline.from_pretrained(repo_id)
|
||||
print(pipeline)
|
||||
```
|
||||
|
||||
위의 코드 출력 결과를 확인해보면, `pipeline`은 [`StableDiffusionPipeline`]의 인스턴스이며, 다음과 같이 총 7개의 컴포넌트로 구성된다는 것을 알 수 있습니다.
|
||||
|
||||
- `"feature_extractor"`: [`~transformers.CLIPFeatureExtractor`]의 인스턴스
|
||||
- `"safety_checker"`: 유해한 컨텐츠를 스크리닝하기 위한 [컴포넌트](https://github.com/huggingface/diffusers/blob/e55687e1e15407f60f32242027b7bb8170e58266/src/diffusers/pipelines/stable_diffusion/safety_checker.py#L32)
|
||||
- `"scheduler"`: [`PNDMScheduler`]의 인스턴스
|
||||
- `"text_encoder"`: [`~transformers.CLIPTextModel`]의 인스턴스
|
||||
- `"tokenizer"`: a [`~transformers.CLIPTokenizer`]의 인스턴스
|
||||
- `"unet"`: [`UNet2DConditionModel`]의 인스턴스
|
||||
- `"vae"` [`AutoencoderKL`]의 인스턴스
|
||||
|
||||
```json
|
||||
StableDiffusionPipeline {
|
||||
"feature_extractor": [
|
||||
"transformers",
|
||||
"CLIPImageProcessor"
|
||||
],
|
||||
"safety_checker": [
|
||||
"stable_diffusion",
|
||||
"StableDiffusionSafetyChecker"
|
||||
],
|
||||
"scheduler": [
|
||||
"diffusers",
|
||||
"PNDMScheduler"
|
||||
],
|
||||
"text_encoder": [
|
||||
"transformers",
|
||||
"CLIPTextModel"
|
||||
],
|
||||
"tokenizer": [
|
||||
"transformers",
|
||||
"CLIPTokenizer"
|
||||
],
|
||||
"unet": [
|
||||
"diffusers",
|
||||
"UNet2DConditionModel"
|
||||
],
|
||||
"vae": [
|
||||
"diffusers",
|
||||
"AutoencoderKL"
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
파이프라인 인스턴스의 컴포넌트들을 [`runwayml/stable-diffusion-v1-5`](https://huggingface.co/runwayml/stable-diffusion-v1-5)의 폴더 구조와 비교해볼 경우, 각각의 컴포넌트마다 별도의 폴더가 있음을 확인할 수 있습니다.
|
||||
|
||||
```
|
||||
.
|
||||
├── feature_extractor
|
||||
│ └── preprocessor_config.json
|
||||
├── model_index.json
|
||||
├── safety_checker
|
||||
│ ├── config.json
|
||||
│ └── pytorch_model.bin
|
||||
├── scheduler
|
||||
│ └── scheduler_config.json
|
||||
├── text_encoder
|
||||
│ ├── config.json
|
||||
│ └── pytorch_model.bin
|
||||
├── tokenizer
|
||||
│ ├── merges.txt
|
||||
│ ├── special_tokens_map.json
|
||||
│ ├── tokenizer_config.json
|
||||
│ └── vocab.json
|
||||
├── unet
|
||||
│ ├── config.json
|
||||
│ ├── diffusion_pytorch_model.bin
|
||||
└── vae
|
||||
├── config.json
|
||||
├── diffusion_pytorch_model.bin
|
||||
```
|
||||
|
||||
또한 각각의 컴포넌트들을 파이프라인 인스턴스의 속성으로써 참조할 수 있습니다.
|
||||
|
||||
```py
|
||||
pipeline.tokenizer
|
||||
```
|
||||
|
||||
```python
|
||||
CLIPTokenizer(
|
||||
name_or_path="/root/.cache/huggingface/hub/models--runwayml--stable-diffusion-v1-5/snapshots/39593d5650112b4cc580433f6b0435385882d819/tokenizer",
|
||||
vocab_size=49408,
|
||||
model_max_length=77,
|
||||
is_fast=False,
|
||||
padding_side="right",
|
||||
truncation_side="right",
|
||||
special_tokens={
|
||||
"bos_token": AddedToken("<|startoftext|>", rstrip=False, lstrip=False, single_word=False, normalized=True),
|
||||
"eos_token": AddedToken("<|endoftext|>", rstrip=False, lstrip=False, single_word=False, normalized=True),
|
||||
"unk_token": AddedToken("<|endoftext|>", rstrip=False, lstrip=False, single_word=False, normalized=True),
|
||||
"pad_token": "<|endoftext|>",
|
||||
},
|
||||
)
|
||||
```
|
||||
|
||||
모든 파이프라인은 `model_index.json` 파일을 통해 [`DiffusionPipeline`]에 다음과 같은 정보를 전달합니다.
|
||||
|
||||
- `_class_name` 는 어떤 파이프라인 클래스를 사용해야 하는지에 대해 알려줍니다.
|
||||
- `_diffusers_version`는 어떤 버전의 디퓨저스로 파이프라인 안의 모델들이 만들어졌는지를 알려줍니다.
|
||||
- 그 다음은 각각의 컴포넌트들이 어떤 라이브러리의 어떤 클래스로 만들어졌는지에 대해 알려줍니다. (아래 예시에서 `"feature_extractor" : ["transformers", "CLIPImageProcessor"]`의 경우, `feature_extractor` 컴포넌트는 `transformers` 라이브러리의 `CLIPImageProcessor` 클래스를 통해 만들어졌다는 것을 의미합니다.)
|
||||
|
||||
```json
|
||||
{
|
||||
"_class_name": "StableDiffusionPipeline",
|
||||
"_diffusers_version": "0.6.0",
|
||||
"feature_extractor": [
|
||||
"transformers",
|
||||
"CLIPImageProcessor"
|
||||
],
|
||||
"safety_checker": [
|
||||
"stable_diffusion",
|
||||
"StableDiffusionSafetyChecker"
|
||||
],
|
||||
"scheduler": [
|
||||
"diffusers",
|
||||
"PNDMScheduler"
|
||||
],
|
||||
"text_encoder": [
|
||||
"transformers",
|
||||
"CLIPTextModel"
|
||||
],
|
||||
"tokenizer": [
|
||||
"transformers",
|
||||
"CLIPTokenizer"
|
||||
],
|
||||
"unet": [
|
||||
"diffusers",
|
||||
"UNet2DConditionModel"
|
||||
],
|
||||
"vae": [
|
||||
"diffusers",
|
||||
"AutoencoderKL"
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
@@ -0,0 +1,18 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# Overview
|
||||
|
||||
🧨 Diffusers는 생성 작업을 위한 다양한 파이프라인, 모델, 스케줄러를 제공합니다. 이러한 컴포넌트를 최대한 간단하게 로드할 수 있도록 단일 통합 메서드인 `from_pretrained()`를 제공하여 Hugging Face [Hub](https://huggingface.co/models?library=diffusers&sort=downloads) 또는 로컬 머신에서 이러한 컴포넌트를 불러올 수 있습니다. 파이프라인이나 모델을 로드할 때마다, 최신 파일이 자동으로 다운로드되고 캐시되므로, 다음에 파일을 다시 다운로드하지 않고도 빠르게 재사용할 수 있습니다.
|
||||
|
||||
이 섹션은 파이프라인 로딩, 파이프라인에서 다양한 컴포넌트를 로드하는 방법, 체크포인트 variants를 불러오는 방법, 그리고 커뮤니티 파이프라인을 불러오는 방법에 대해 알아야 할 모든 것들을 다룹니다. 또한 스케줄러를 불러오는 방법과 서로 다른 스케줄러를 사용할 때 발생하는 속도와 품질간의 트레이드 오프를 비교하는 방법 역시 다룹니다. 그리고 마지막으로 🧨 Diffusers와 함께 파이토치에서 사용할 수 있도록 KerasCV 체크포인트를 변환하고 불러오는 방법을 살펴봅니다.
|
||||
|
||||
@@ -0,0 +1,191 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# 다양한 Stable Diffusion 포맷 불러오기
|
||||
|
||||
Stable Diffusion 모델들은 학습 및 저장된 프레임워크와 다운로드 위치에 따라 다양한 형식으로 제공됩니다. 이러한 형식을 🤗 Diffusers에서 사용할 수 있도록 변환하면 추론을 위한 [다양한 스케줄러 사용](schedulers), 사용자 지정 파이프라인 구축, 추론 속도 최적화를 위한 다양한 기법과 방법 등 라이브러리에서 지원하는 모든 기능을 사용할 수 있습니다.
|
||||
|
||||
<Tip>
|
||||
|
||||
우리는 `.safetensors` 형식을 추천합니다. 왜냐하면 기존의 pickled 파일은 취약하고 머신에서 코드를 실행할 때 악용될 수 있는 것에 비해 훨씬 더 안전합니다. (safetensors 불러오기 가이드에서 자세히 알아보세요.)
|
||||
|
||||
</Tip>
|
||||
|
||||
이 가이드에서는 다른 Stable Diffusion 형식을 🤗 Diffusers와 호환되도록 변환하는 방법을 설명합니다.
|
||||
|
||||
## PyTorch .ckpt
|
||||
|
||||
체크포인트 또는 `.ckpt` 형식은 일반적으로 모델을 저장하는 데 사용됩니다. `.ckpt` 파일은 전체 모델을 포함하며 일반적으로 크기가 몇 GB입니다. `.ckpt` 파일을 [~StableDiffusionPipeline.from_ckpt] 메서드를 사용하여 직접 불러와서 사용할 수도 있지만, 일반적으로 두 가지 형식을 모두 사용할 수 있도록 `.ckpt` 파일을 🤗 Diffusers로 변환하는 것이 더 좋습니다.
|
||||
|
||||
`.ckpt` 파일을 변환하는 두 가지 옵션이 있습니다. Space를 사용하여 체크포인트를 변환하거나 스크립트를 사용하여 `.ckpt` 파일을 변환합니다.
|
||||
|
||||
### Space로 변환하기
|
||||
|
||||
`.ckpt` 파일을 변환하는 가장 쉽고 편리한 방법은 SD에서 Diffusers로 스페이스를 사용하는 것입니다. Space의 지침에 따라 .ckpt 파일을 변환 할 수 있습니다.
|
||||
|
||||
이 접근 방식은 기본 모델에서는 잘 작동하지만 더 많은 사용자 정의 모델에서는 어려움을 겪을 수 있습니다. 빈 pull request나 오류를 반환하면 Space가 실패한 것입니다.
|
||||
이 경우 스크립트를 사용하여 `.ckpt` 파일을 변환해 볼 수 있습니다.
|
||||
|
||||
### 스크립트로 변환하기
|
||||
|
||||
🤗 Diffusers는 `.ckpt` 파일 변환을 위한 변환 스크립트를 제공합니다. 이 접근 방식은 위의 Space보다 더 안정적입니다.
|
||||
|
||||
시작하기 전에 스크립트를 실행할 🤗 Diffusers의 로컬 클론(clone)이 있는지 확인하고 Hugging Face 계정에 로그인하여 pull request를 열고 변환된 모델을 허브에 푸시할 수 있도록 하세요.
|
||||
|
||||
```bash
|
||||
huggingface-cli login
|
||||
```
|
||||
|
||||
스크립트를 사용하려면:
|
||||
|
||||
1. 변환하려는 `.ckpt` 파일이 포함된 리포지토리를 Git으로 클론(clone)합니다.
|
||||
|
||||
이 예제에서는 TemporalNet .ckpt 파일을 변환해 보겠습니다:
|
||||
|
||||
```bash
|
||||
git lfs install
|
||||
git clone https://huggingface.co/CiaraRowles/TemporalNet
|
||||
```
|
||||
|
||||
2. 체크포인트를 변환할 리포지토리에서 pull request를 엽니다:
|
||||
|
||||
```bash
|
||||
cd TemporalNet && git fetch origin refs/pr/13:pr/13
|
||||
git checkout pr/13
|
||||
```
|
||||
|
||||
3. 변환 스크립트에서 구성할 입력 인수는 여러 가지가 있지만 가장 중요한 인수는 다음과 같습니다:
|
||||
|
||||
- `checkpoint_path`: 변환할 `.ckpt` 파일의 경로를 입력합니다.
|
||||
- `original_config_file`: 원래 아키텍처의 구성을 정의하는 YAML 파일입니다. 이 파일을 찾을 수 없는 경우 `.ckpt` 파일을 찾은 GitHub 리포지토리에서 YAML 파일을 검색해 보세요.
|
||||
- `dump_path`: 변환된 모델의 경로
|
||||
|
||||
예를 들어, TemporalNet 모델은 Stable Diffusion v1.5 및 ControlNet 모델이기 때문에 ControlNet 리포지토리에서 cldm_v15.yaml 파일을 가져올 수 있습니다.
|
||||
|
||||
4. 이제 스크립트를 실행하여 .ckpt 파일을 변환할 수 있습니다:
|
||||
|
||||
```bash
|
||||
python ../diffusers/scripts/convert_original_stable_diffusion_to_diffusers.py --checkpoint_path temporalnetv3.ckpt --original_config_file cldm_v15.yaml --dump_path ./ --controlnet
|
||||
```
|
||||
|
||||
5. 변환이 완료되면 변환된 모델을 업로드하고 결과물을 pull request [pull request](https://huggingface.co/CiaraRowles/TemporalNet/discussions/13)를 테스트하세요!
|
||||
|
||||
```bash
|
||||
git push origin pr/13:refs/pr/13
|
||||
```
|
||||
|
||||
## **Keras .pb or .h5**
|
||||
|
||||
🧪 이 기능은 실험적인 기능입니다. 현재로서는 Stable Diffusion v1 체크포인트만 변환 KerasCV Space에서 지원됩니다.
|
||||
|
||||
[KerasCV](https://keras.io/keras_cv/)는 [Stable Diffusion](https://github.com/keras-team/keras-cv/blob/master/keras_cv/models/stable_diffusion) v1 및 v2에 대한 학습을 지원합니다. 그러나 추론 및 배포를 위한 Stable Diffusion 모델 실험을 제한적으로 지원하는 반면, 🤗 Diffusers는 다양한 [noise schedulers](https://huggingface.co/docs/diffusers/using-diffusers/schedulers), [flash attention](https://huggingface.co/docs/diffusers/optimization/xformers), and [other optimization techniques](https://huggingface.co/docs/diffusers/optimization/fp16) 등 이러한 목적을 위한 보다 완벽한 기능을 갖추고 있습니다.
|
||||
|
||||
[Convert KerasCV](https://huggingface.co/spaces/sayakpaul/convert-kerascv-sd-diffusers) Space 변환은 `.pb` 또는 `.h5`을 PyTorch로 변환한 다음, 추론할 수 있도록 [`StableDiffusionPipeline`] 으로 감싸서 준비합니다. 변환된 체크포인트는 Hugging Face Hub의 리포지토리에 저장됩니다.
|
||||
|
||||
예제로, textual-inversion으로 학습된 `[sayakpaul/textual-inversion-kerasio](https://huggingface.co/sayakpaul/textual-inversion-kerasio/tree/main)` 체크포인트를 변환해 보겠습니다. 이것은 특수 토큰 `<my-funny-cat>`을 사용하여 고양이로 이미지를 개인화합니다.
|
||||
|
||||
KerasCV Space 변환에서는 다음을 입력할 수 있습니다:
|
||||
|
||||
- Hugging Face 토큰.
|
||||
- UNet 과 텍스트 인코더(text encoder) 가중치를 다운로드하는 경로입니다. 모델을 어떻게 학습할지 방식에 따라, UNet과 텍스트 인코더의 경로를 모두 제공할 필요는 없습니다. 예를 들어, textual-inversion에는 텍스트 인코더의 임베딩만 필요하고 텍스트-이미지(text-to-image) 모델 변환에는 UNet 가중치만 필요합니다.
|
||||
- Placeholder 토큰은 textual-inversion 모델에만 적용됩니다.
|
||||
- `output_repo_prefix`는 변환된 모델이 저장되는 리포지토리의 이름입니다.
|
||||
|
||||
**Submit** (제출) 버튼을 클릭하면 KerasCV 체크포인트가 자동으로 변환됩니다! 체크포인트가 성공적으로 변환되면, 변환된 체크포인트가 포함된 새 리포지토리로 연결되는 링크가 표시됩니다. 새 리포지토리로 연결되는 링크를 따라가면 변환된 모델을 사용해 볼 수 있는 추론 위젯이 포함된 모델 카드가 생성된 KerasCV Space 변환을 확인할 수 있습니다.
|
||||
|
||||
코드를 사용하여 추론을 실행하려면 모델 카드의 오른쪽 상단 모서리에 있는 **Use in Diffusers** 버튼을 클릭하여 예시 코드를 복사하여 붙여넣습니다:
|
||||
|
||||
```py
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
pipeline = DiffusionPipeline.from_pretrained("sayakpaul/textual-inversion-cat-kerascv_sd_diffusers_pipeline")
|
||||
```
|
||||
|
||||
그러면 다음과 같은 이미지를 생성할 수 있습니다:
|
||||
|
||||
```py
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
pipeline = DiffusionPipeline.from_pretrained("sayakpaul/textual-inversion-cat-kerascv_sd_diffusers_pipeline")
|
||||
pipeline.to("cuda")
|
||||
|
||||
placeholder_token = "<my-funny-cat-token>"
|
||||
prompt = f"two {placeholder_token} getting married, photorealistic, high quality"
|
||||
image = pipeline(prompt, num_inference_steps=50).images[0]
|
||||
```
|
||||
|
||||
## **A1111 LoRA files**
|
||||
|
||||
[Automatic1111](https://github.com/AUTOMATIC1111/stable-diffusion-webui) (A1111)은 Stable Diffusion을 위해 널리 사용되는 웹 UI로, [Civitai](https://civitai.com/) 와 같은 모델 공유 플랫폼을 지원합니다. 특히 LoRA 기법으로 학습된 모델은 학습 속도가 빠르고 완전히 파인튜닝된 모델보다 파일 크기가 훨씬 작기 때문에 인기가 높습니다.
|
||||
|
||||
🤗 Diffusers는 [`~loaders.LoraLoaderMixin.load_lora_weights`]:를 사용하여 A1111 LoRA 체크포인트 불러오기를 지원합니다:
|
||||
|
||||
```py
|
||||
from MuseVdiffusers import DiffusionPipeline, UniPCMultistepScheduler
|
||||
import torch
|
||||
|
||||
pipeline = DiffusionPipeline.from_pretrained(
|
||||
"andite/anything-v4.0", torch_dtype=torch.float16, safety_checker=None
|
||||
).to("cuda")
|
||||
pipeline.scheduler = UniPCMultistepScheduler.from_config(pipeline.scheduler.config)
|
||||
```
|
||||
|
||||
Civitai에서 LoRA 체크포인트를 다운로드하세요; 이 예제에서는 [Howls Moving Castle,Interior/Scenery LoRA (Ghibli Stlye)](https://civitai.com/models/14605?modelVersionId=19998) 체크포인트를 사용했지만, 어떤 LoRA 체크포인트든 자유롭게 사용해 보세요!
|
||||
|
||||
```bash
|
||||
!wget https://civitai.com/api/download/models/19998 -O howls_moving_castle.safetensors
|
||||
```
|
||||
|
||||
메서드를 사용하여 파이프라인에 LoRA 체크포인트를 불러옵니다:
|
||||
|
||||
```py
|
||||
pipeline.load_lora_weights(".", weight_name="howls_moving_castle.safetensors")
|
||||
```
|
||||
|
||||
이제 파이프라인을 사용하여 이미지를 생성할 수 있습니다:
|
||||
|
||||
```py
|
||||
prompt = "masterpiece, illustration, ultra-detailed, cityscape, san francisco, golden gate bridge, california, bay area, in the snow, beautiful detailed starry sky"
|
||||
negative_prompt = "lowres, cropped, worst quality, low quality, normal quality, artifacts, signature, watermark, username, blurry, more than one bridge, bad architecture"
|
||||
|
||||
images = pipeline(
|
||||
prompt=prompt,
|
||||
negative_prompt=negative_prompt,
|
||||
width=512,
|
||||
height=512,
|
||||
num_inference_steps=25,
|
||||
num_images_per_prompt=4,
|
||||
generator=torch.manual_seed(0),
|
||||
).images
|
||||
```
|
||||
|
||||
마지막으로, 디스플레이에 이미지를 표시하는 헬퍼 함수를 만듭니다:
|
||||
|
||||
```py
|
||||
from PIL import Image
|
||||
|
||||
|
||||
def image_grid(imgs, rows=2, cols=2):
|
||||
w, h = imgs[0].size
|
||||
grid = Image.new("RGB", size=(cols * w, rows * h))
|
||||
|
||||
for i, img in enumerate(imgs):
|
||||
grid.paste(img, box=(i % cols * w, i // cols * h))
|
||||
return grid
|
||||
|
||||
|
||||
image_grid(images)
|
||||
```
|
||||
|
||||
<div class="flex justify-center">
|
||||
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/a1111-lora-sf.png" />
|
||||
</div>
|
||||
@@ -0,0 +1,17 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# Overview
|
||||
|
||||
파이프라인은 독립적으로 훈련된 모델과 스케줄러를 함께 모아서 추론을 위해 diffusion 시스템을 빠르고 쉽게 사용할 수 있는 방법을 제공하는 end-to-end 클래스입니다. 모델과 스케줄러의 특정 조합은 특수한 기능과 함께 [`StableDiffusionPipeline`] 또는 [`StableDiffusionControlNetPipeline`]과 같은 특정 파이프라인 유형을 정의합니다. 모든 파이프라인 유형은 기본 [`DiffusionPipeline`] 클래스에서 상속됩니다. 어느 체크포인트를 전달하면, 파이프라인 유형을 자동으로 감지하고 필요한 구성 요소들을 불러옵니다.
|
||||
|
||||
이 섹션에서는 unconditional 이미지 생성, text-to-image 생성의 다양한 테크닉과 변화를 파이프라인에서 지원하는 작업들을 소개합니다. 프롬프트에 있는 특정 단어가 출력에 영향을 미치는 것을 조정하기 위해 재현성을 위한 시드 설정과 프롬프트에 가중치를 부여하는 것으로 생성 프로세스를 더 잘 제어하는 방법에 대해 배울 수 있습니다. 마지막으로 음성에서부터 이미지 생성과 같은 커스텀 작업을 위한 커뮤니티 파이프라인을 만드는 방법을 알 수 있습니다.
|
||||
@@ -0,0 +1,201 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# 재현 가능한 파이프라인 생성하기
|
||||
|
||||
[[open-in-colab]]
|
||||
|
||||
재현성은 테스트, 결과 재현, 그리고 [이미지 퀄리티 높이기](resuing_seeds)에서 중요합니다.
|
||||
그러나 diffusion 모델의 무작위성은 매번 모델이 돌아갈 때마다 파이프라인이 다른 이미지를 생성할 수 있도록 하는 이유로 필요합니다.
|
||||
플랫폼 간에 정확하게 동일한 결과를 얻을 수는 없지만, 특정 허용 범위 내에서 릴리스 및 플랫폼 간에 결과를 재현할 수는 있습니다.
|
||||
그럼에도 diffusion 파이프라인과 체크포인트에 따라 허용 오차가 달라집니다.
|
||||
|
||||
diffusion 모델에서 무작위성의 원천을 제어하거나 결정론적 알고리즘을 사용하는 방법을 이해하는 것이 중요한 이유입니다.
|
||||
|
||||
<Tip>
|
||||
|
||||
💡 Pytorch의 [재현성에 대한 선언](https://pytorch.org/docs/stable/notes/randomness.html)를 꼭 읽어보길 추천합니다:
|
||||
|
||||
> 완전하게 재현가능한 결과는 Pytorch 배포, 개별적인 커밋, 혹은 다른 플랫폼들에서 보장되지 않습니다.
|
||||
> 또한, 결과는 CPU와 GPU 실행간에 심지어 같은 seed를 사용할 때도 재현 가능하지 않을 수 있습니다.
|
||||
|
||||
</Tip>
|
||||
|
||||
## 무작위성 제어하기
|
||||
|
||||
추론에서, 파이프라인은 노이즈를 줄이기 위해 가우시안 노이즈를 생성하거나 스케줄링 단계에 노이즈를 더하는 등의 랜덤 샘플링 실행에 크게 의존합니다,
|
||||
|
||||
[DDIMPipeline](https://huggingface.co/docs/diffusers/v0.18.0/en/api/pipelines/ddim#diffusers.DDIMPipeline)에서 두 추론 단계 이후의 텐서 값을 살펴보세요:
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DDIMPipeline
|
||||
import numpy as np
|
||||
|
||||
model_id = "google/ddpm-cifar10-32"
|
||||
|
||||
# 모델과 스케줄러를 불러오기
|
||||
ddim = DDIMPipeline.from_pretrained(model_id)
|
||||
|
||||
# 두 개의 단계에 대해서 파이프라인을 실행하고 numpy tensor로 값을 반환하기
|
||||
image = ddim(num_inference_steps=2, output_type="np").images
|
||||
print(np.abs(image).sum())
|
||||
```
|
||||
|
||||
위의 코드를 실행하면 하나의 값이 나오지만, 다시 실행하면 다른 값이 나옵니다. 무슨 일이 일어나고 있는 걸까요?
|
||||
|
||||
파이프라인이 실행될 때마다, [torch.randn](https://pytorch.org/docs/stable/generated/torch.randn.html)은
|
||||
단계적으로 노이즈 제거되는 가우시안 노이즈가 생성하기 위한 다른 랜덤 seed를 사용합니다.
|
||||
|
||||
그러나 동일한 이미지를 안정적으로 생성해야 하는 경우에는 CPU에서 파이프라인을 실행하는지 GPU에서 실행하는지에 따라 달라집니다.
|
||||
|
||||
### CPU
|
||||
|
||||
CPU에서 재현 가능한 결과를 생성하려면, PyTorch [Generator](https://pytorch.org/docs/stable/generated/torch.randn.html)로 seed를 고정합니다:
|
||||
|
||||
```python
|
||||
import torch
|
||||
from MuseVdiffusers import DDIMPipeline
|
||||
import numpy as np
|
||||
|
||||
model_id = "google/ddpm-cifar10-32"
|
||||
|
||||
# 모델과 스케줄러 불러오기
|
||||
ddim = DDIMPipeline.from_pretrained(model_id)
|
||||
|
||||
# 재현성을 위해 generator 만들기
|
||||
generator = torch.Generator(device="cpu").manual_seed(0)
|
||||
|
||||
# 두 개의 단계에 대해서 파이프라인을 실행하고 numpy tensor로 값을 반환하기
|
||||
image = ddim(num_inference_steps=2, output_type="np", generator=generator).images
|
||||
print(np.abs(image).sum())
|
||||
```
|
||||
|
||||
이제 위의 코드를 실행하면 seed를 가진 `Generator` 객체가 파이프라인의 모든 랜덤 함수에 전달되므로 항상 `1491.1711` 값이 출력됩니다.
|
||||
|
||||
특정 하드웨어 및 PyTorch 버전에서 이 코드 예제를 실행하면 동일하지는 않더라도 유사한 결과를 얻을 수 있습니다.
|
||||
|
||||
<Tip>
|
||||
|
||||
💡 처음에는 시드를 나타내는 정수값 대신에 `Generator` 개체를 파이프라인에 전달하는 것이 약간 비직관적일 수 있지만,
|
||||
`Generator`는 순차적으로 여러 파이프라인에 전달될 수 있는 \랜덤상태\이기 때문에 PyTorch에서 확률론적 모델을 다룰 때 권장되는 설계입니다.
|
||||
|
||||
</Tip>
|
||||
|
||||
### GPU
|
||||
|
||||
예를 들면, GPU 상에서 같은 코드 예시를 실행하면:
|
||||
|
||||
```python
|
||||
import torch
|
||||
from MuseVdiffusers import DDIMPipeline
|
||||
import numpy as np
|
||||
|
||||
model_id = "google/ddpm-cifar10-32"
|
||||
|
||||
# 모델과 스케줄러 불러오기
|
||||
ddim = DDIMPipeline.from_pretrained(model_id)
|
||||
ddim.to("cuda")
|
||||
|
||||
# 재현성을 위한 generator 만들기
|
||||
generator = torch.Generator(device="cuda").manual_seed(0)
|
||||
|
||||
# 두 개의 단계에 대해서 파이프라인을 실행하고 numpy tensor로 값을 반환하기
|
||||
image = ddim(num_inference_steps=2, output_type="np", generator=generator).images
|
||||
print(np.abs(image).sum())
|
||||
```
|
||||
|
||||
GPU가 CPU와 다른 난수 생성기를 사용하기 때문에 동일한 시드를 사용하더라도 결과가 같지 않습니다.
|
||||
|
||||
이 문제를 피하기 위해 🧨 Diffusers는 CPU에 임의의 노이즈를 생성한 다음 필요에 따라 텐서를 GPU로 이동시키는
|
||||
[randn_tensor()](https://huggingface.co/docs/diffusers/v0.18.0/en/api/utilities#diffusers.utils.randn_tensor)기능을 가지고 있습니다.
|
||||
`randn_tensor` 기능은 파이프라인 내부 어디에서나 사용되므로 파이프라인이 GPU에서 실행되더라도 **항상** CPU `Generator`를 통과할 수 있습니다.
|
||||
|
||||
이제 결과에 훨씬 더 다가왔습니다!
|
||||
|
||||
```python
|
||||
import torch
|
||||
from MuseVdiffusers import DDIMPipeline
|
||||
import numpy as np
|
||||
|
||||
model_id = "google/ddpm-cifar10-32"
|
||||
|
||||
# 모델과 스케줄러 불러오기
|
||||
ddim = DDIMPipeline.from_pretrained(model_id)
|
||||
ddim.to("cuda")
|
||||
|
||||
#재현성을 위한 generator 만들기 (GPU에 올리지 않도록 조심한다!)
|
||||
generator = torch.manual_seed(0)
|
||||
|
||||
# 두 개의 단계에 대해서 파이프라인을 실행하고 numpy tensor로 값을 반환하기
|
||||
image = ddim(num_inference_steps=2, output_type="np", generator=generator).images
|
||||
print(np.abs(image).sum())
|
||||
```
|
||||
|
||||
<Tip>
|
||||
|
||||
💡 재현성이 중요한 경우에는 항상 CPU generator를 전달하는 것이 좋습니다.
|
||||
성능 손실은 무시할 수 없는 경우가 많으며 파이프라인이 GPU에서 실행되었을 때보다 훨씬 더 비슷한 값을 생성할 수 있습니다.
|
||||
|
||||
</Tip>
|
||||
|
||||
마지막으로 [UnCLIPPipeline](https://huggingface.co/docs/diffusers/v0.18.0/en/api/pipelines/unclip#diffusers.UnCLIPPipeline)과 같은
|
||||
더 복잡한 파이프라인의 경우, 이들은 종종 정밀 오차 전파에 극도로 취약합니다.
|
||||
다른 GPU 하드웨어 또는 PyTorch 버전에서 유사한 결과를 기대하지 마세요.
|
||||
이 경우 완전한 재현성을 위해 완전히 동일한 하드웨어 및 PyTorch 버전을 실행해야 합니다.
|
||||
|
||||
## 결정론적 알고리즘
|
||||
|
||||
결정론적 알고리즘을 사용하여 재현 가능한 파이프라인을 생성하도록 PyTorch를 구성할 수도 있습니다.
|
||||
그러나 결정론적 알고리즘은 비결정론적 알고리즘보다 느리고 성능이 저하될 수 있습니다.
|
||||
하지만 재현성이 중요하다면, 이것이 최선의 방법입니다!
|
||||
|
||||
둘 이상의 CUDA 스트림에서 작업이 시작될 때 비결정론적 동작이 발생합니다.
|
||||
이 문제를 방지하려면 환경 변수 [CUBLAS_WORKSPACE_CONFIG](https://docs.nvidia.com/cuda/cublas/index.html#results-reproducibility)를 `:16:8`로 설정해서
|
||||
런타임 중에 오직 하나의 버퍼 크리만 사용하도록 설정합니다.
|
||||
|
||||
PyTorch는 일반적으로 가장 빠른 알고리즘을 선택하기 위해 여러 알고리즘을 벤치마킹합니다.
|
||||
하지만 재현성을 원하는 경우, 벤치마크가 매 순간 다른 알고리즘을 선택할 수 있기 때문에 이 기능을 사용하지 않도록 설정해야 합니다.
|
||||
마지막으로, [torch.use_deterministic_algorithms](https://pytorch.org/docs/stable/generated/torch.use_deterministic_algorithms.html)에
|
||||
`True`를 통과시켜 결정론적 알고리즘이 활성화 되도록 합니다.
|
||||
|
||||
```py
|
||||
import os
|
||||
|
||||
os.environ["CUBLAS_WORKSPACE_CONFIG"] = ":16:8"
|
||||
|
||||
torch.backends.cudnn.benchmark = False
|
||||
torch.use_deterministic_algorithms(True)
|
||||
```
|
||||
|
||||
이제 동일한 파이프라인을 두번 실행하면 동일한 결과를 얻을 수 있습니다.
|
||||
|
||||
```py
|
||||
import torch
|
||||
from MuseVdiffusers import DDIMScheduler, StableDiffusionPipeline
|
||||
import numpy as np
|
||||
|
||||
model_id = "runwayml/stable-diffusion-v1-5"
|
||||
pipe = StableDiffusionPipeline.from_pretrained(model_id).to("cuda")
|
||||
pipe.scheduler = DDIMScheduler.from_config(pipe.scheduler.config)
|
||||
g = torch.Generator(device="cuda")
|
||||
|
||||
prompt = "A bear is playing a guitar on Times Square"
|
||||
|
||||
g.manual_seed(0)
|
||||
result1 = pipe(prompt=prompt, num_inference_steps=50, generator=g, output_type="latent").images
|
||||
|
||||
g.manual_seed(0)
|
||||
result2 = pipe(prompt=prompt, num_inference_steps=50, generator=g, output_type="latent").images
|
||||
|
||||
print("L_inf dist = ", abs(result1 - result2).max())
|
||||
"L_inf dist = tensor(0., device='cuda:0')"
|
||||
```
|
||||
@@ -0,0 +1,63 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# Deterministic(결정적) 생성을 통한 이미지 품질 개선
|
||||
|
||||
생성된 이미지의 품질을 개선하는 일반적인 방법은 *결정적 batch(배치) 생성*을 사용하는 것입니다. 이 방법은 이미지 batch(배치)를 생성하고 두 번째 추론 라운드에서 더 자세한 프롬프트와 함께 개선할 이미지 하나를 선택하는 것입니다. 핵심은 일괄 이미지 생성을 위해 파이프라인에 [`torch.Generator`](https://pytorch.org/docs/stable/generated/torch.Generator.html#generator) 목록을 전달하고, 각 `Generator`를 시드에 연결하여 이미지에 재사용할 수 있도록 하는 것입니다.
|
||||
|
||||
예를 들어 [`runwayml/stable-diffusion-v1-5`](runwayml/stable-diffusion-v1-5)를 사용하여 다음 프롬프트의 여러 버전을 생성해 봅시다.
|
||||
|
||||
```py
|
||||
prompt = "Labrador in the style of Vermeer"
|
||||
```
|
||||
|
||||
(가능하다면) 파이프라인을 [`DiffusionPipeline.from_pretrained`]로 인스턴스화하여 GPU에 배치합니다.
|
||||
|
||||
```python
|
||||
>>> from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
>>> pipe = DiffusionPipeline.from_pretrained("runwayml/stable-diffusion-v1-5", torch_dtype=torch.float16)
|
||||
>>> pipe = pipe.to("cuda")
|
||||
```
|
||||
|
||||
이제 네 개의 서로 다른 `Generator`를 정의하고 각 `Generator`에 시드(`0` ~ `3`)를 할당하여 나중에 특정 이미지에 대해 `Generator`를 재사용할 수 있도록 합니다.
|
||||
|
||||
```python
|
||||
>>> import torch
|
||||
|
||||
>>> generator = [torch.Generator(device="cuda").manual_seed(i) for i in range(4)]
|
||||
```
|
||||
|
||||
이미지를 생성하고 살펴봅니다.
|
||||
|
||||
```python
|
||||
>>> images = pipe(prompt, generator=generator, num_images_per_prompt=4).images
|
||||
>>> images
|
||||
```
|
||||
|
||||
|
||||
|
||||
이 예제에서는 첫 번째 이미지를 개선했지만 실제로는 원하는 모든 이미지를 사용할 수 있습니다(심지어 두 개의 눈이 있는 이미지도!). 첫 번째 이미지에서는 시드가 '0'인 '생성기'를 사용했기 때문에 두 번째 추론 라운드에서는 이 '생성기'를 재사용할 것입니다. 이미지의 품질을 개선하려면 프롬프트에 몇 가지 텍스트를 추가합니다:
|
||||
|
||||
```python
|
||||
prompt = [prompt + t for t in [", highly realistic", ", artsy", ", trending", ", colorful"]]
|
||||
generator = [torch.Generator(device="cuda").manual_seed(0) for i in range(4)]
|
||||
```
|
||||
|
||||
시드가 `0`인 제너레이터 4개를 생성하고, 이전 라운드의 첫 번째 이미지처럼 보이는 다른 이미지 batch(배치)를 생성합니다!
|
||||
|
||||
```python
|
||||
>>> images = pipe(prompt, generator=generator).images
|
||||
>>> images
|
||||
```
|
||||
|
||||
|
||||
@@ -0,0 +1,329 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# 스케줄러
|
||||
|
||||
diffusion 파이프라인은 diffusion 모델, 스케줄러 등의 컴포넌트들로 구성됩니다. 그리고 파이프라인 안의 일부 컴포넌트를 다른 컴포넌트로 교체하는 식의 커스터마이징 역시 가능합니다. 이와 같은 컴포넌트 커스터마이징의 가장 대표적인 예시가 바로 [스케줄러](../api/schedulers/overview.md)를 교체하는 것입니다.
|
||||
|
||||
|
||||
|
||||
스케쥴러는 다음과 같이 diffusion 시스템의 전반적인 디노이징 프로세스를 정의합니다.
|
||||
|
||||
- 디노이징 스텝을 얼마나 가져가야 할까?
|
||||
- 확률적으로(stochastic) 혹은 확정적으로(deterministic)?
|
||||
- 디노이징 된 샘플을 찾아내기 위해 어떤 알고리즘을 사용해야 할까?
|
||||
|
||||
이러한 프로세스는 다소 난해하고, 디노이징 속도와 디노이징 퀄리티 사이의 트레이드 오프를 정의해야 하는 문제가 될 수 있습니다. 주어진 파이프라인에 어떤 스케줄러가 가장 적합한지를 정량적으로 판단하는 것은 매우 어려운 일입니다. 이로 인해 일단 해당 스케줄러를 직접 사용하여, 생성되는 이미지를 직접 눈으로 보며, 정성적으로 성능을 판단해보는 것이 추천되곤 합니다.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## 파이프라인 불러오기
|
||||
|
||||
먼저 스테이블 diffusion 파이프라인을 불러오도록 해보겠습니다. 물론 스테이블 diffusion을 사용하기 위해서는, 허깅페이스 허브에 등록된 사용자여야 하며, 관련 [라이센스](https://huggingface.co/runwayml/stable-diffusion-v1-5)에 동의해야 한다는 점을 잊지 말아주세요.
|
||||
|
||||
*역자 주: 다만, 현재 신규로 생성한 허깅페이스 계정에 대해서는 라이센스 동의를 요구하지 않는 것으로 보입니다!*
|
||||
|
||||
```python
|
||||
from huggingface_hub import login
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
import torch
|
||||
|
||||
# first we need to login with our access token
|
||||
login()
|
||||
|
||||
# Now we can download the pipeline
|
||||
pipeline = DiffusionPipeline.from_pretrained("runwayml/stable-diffusion-v1-5", torch_dtype=torch.float16)
|
||||
```
|
||||
|
||||
다음으로, GPU로 이동합니다.
|
||||
|
||||
```python
|
||||
pipeline.to("cuda")
|
||||
```
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## 스케줄러 액세스
|
||||
|
||||
스케줄러는 언제나 파이프라인의 컴포넌트로서 존재하며, 일반적으로 파이프라인 인스턴스 내에 `scheduler`라는 이름의 속성(property)으로 정의되어 있습니다.
|
||||
|
||||
```python
|
||||
pipeline.scheduler
|
||||
```
|
||||
|
||||
**Output**:
|
||||
|
||||
```
|
||||
PNDMScheduler {
|
||||
"_class_name": "PNDMScheduler",
|
||||
"_diffusers_version": "0.8.0.dev0",
|
||||
"beta_end": 0.012,
|
||||
"beta_schedule": "scaled_linear",
|
||||
"beta_start": 0.00085,
|
||||
"clip_sample": false,
|
||||
"num_train_timesteps": 1000,
|
||||
"set_alpha_to_one": false,
|
||||
"skip_prk_steps": true,
|
||||
"steps_offset": 1,
|
||||
"trained_betas": null
|
||||
}
|
||||
```
|
||||
|
||||
출력 결과를 통해, 우리는 해당 스케줄러가 [`PNDMScheduler`]의 인스턴스라는 것을 알 수 있습니다. 이제 [`PNDMScheduler`]와 다른 스케줄러들의 성능을 비교해보도록 하겠습니다. 먼저 테스트에 사용할 프롬프트를 다음과 같이 정의해보도록 하겠습니다.
|
||||
|
||||
```python
|
||||
prompt = "A photograph of an astronaut riding a horse on Mars, high resolution, high definition."
|
||||
```
|
||||
|
||||
다음으로 유사한 이미지 생성을 보장하기 위해서, 다음과 같이 랜덤시드를 고정해주도록 하겠습니다.
|
||||
|
||||
```python
|
||||
generator = torch.Generator(device="cuda").manual_seed(8)
|
||||
image = pipeline(prompt, generator=generator).images[0]
|
||||
image
|
||||
```
|
||||
|
||||
<p align="center">
|
||||
<br>
|
||||
<img src="https://huggingface.co/datasets/patrickvonplaten/images/resolve/main/diffusers_docs/astronaut_pndm.png" width="400"/>
|
||||
<br>
|
||||
</p>
|
||||
|
||||
|
||||
|
||||
|
||||
## 스케줄러 교체하기
|
||||
|
||||
다음으로 파이프라인의 스케줄러를 다른 스케줄러로 교체하는 방법에 대해 알아보겠습니다. 모든 스케줄러는 [`SchedulerMixin.compatibles`]라는 속성(property)을 갖고 있습니다. 해당 속성은 **호환 가능한** 스케줄러들에 대한 정보를 담고 있습니다.
|
||||
|
||||
```python
|
||||
pipeline.scheduler.compatibles
|
||||
```
|
||||
|
||||
**Output**:
|
||||
|
||||
```
|
||||
[diffusers.schedulers.scheduling_lms_discrete.LMSDiscreteScheduler,
|
||||
diffusers.schedulers.scheduling_ddim.DDIMScheduler,
|
||||
diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler,
|
||||
diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler,
|
||||
diffusers.schedulers.scheduling_pndm.PNDMScheduler,
|
||||
diffusers.schedulers.scheduling_ddpm.DDPMScheduler,
|
||||
diffusers.schedulers.scheduling_euler_ancestral_discrete.EulerAncestralDiscreteScheduler]
|
||||
```
|
||||
|
||||
호환되는 스케줄러들을 살펴보면 아래와 같습니다.
|
||||
|
||||
- [`LMSDiscreteScheduler`],
|
||||
- [`DDIMScheduler`],
|
||||
- [`DPMSolverMultistepScheduler`],
|
||||
- [`EulerDiscreteScheduler`],
|
||||
- [`PNDMScheduler`],
|
||||
- [`DDPMScheduler`],
|
||||
- [`EulerAncestralDiscreteScheduler`].
|
||||
|
||||
앞서 정의했던 프롬프트를 사용해서 각각의 스케줄러들을 비교해보도록 하겠습니다.
|
||||
|
||||
먼저 파이프라인 안의 스케줄러를 바꾸기 위해 [`ConfigMixin.config`] 속성과 [`ConfigMixin.from_config`] 메서드를 활용해보려고 합니다.
|
||||
|
||||
|
||||
|
||||
```python
|
||||
pipeline.scheduler.config
|
||||
```
|
||||
|
||||
**Output**:
|
||||
|
||||
```
|
||||
FrozenDict([('num_train_timesteps', 1000),
|
||||
('beta_start', 0.00085),
|
||||
('beta_end', 0.012),
|
||||
('beta_schedule', 'scaled_linear'),
|
||||
('trained_betas', None),
|
||||
('skip_prk_steps', True),
|
||||
('set_alpha_to_one', False),
|
||||
('steps_offset', 1),
|
||||
('_class_name', 'PNDMScheduler'),
|
||||
('_diffusers_version', '0.8.0.dev0'),
|
||||
('clip_sample', False)])
|
||||
```
|
||||
|
||||
기존 스케줄러의 config를 호환 가능한 다른 스케줄러에 이식하는 것 역시 가능합니다.
|
||||
|
||||
다음 예시는 기존 스케줄러(`pipeline.scheduler`)를 다른 종류의 스케줄러(`DDIMScheduler`)로 바꾸는 코드입니다. 기존 스케줄러가 갖고 있던 config를 `.from_config` 메서드의 인자로 전달하는 것을 확인할 수 있습니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DDIMScheduler
|
||||
|
||||
pipeline.scheduler = DDIMScheduler.from_config(pipeline.scheduler.config)
|
||||
```
|
||||
|
||||
|
||||
|
||||
이제 파이프라인을 실행해서 두 스케줄러 사이의 생성된 이미지의 퀄리티를 비교해봅시다.
|
||||
|
||||
```python
|
||||
generator = torch.Generator(device="cuda").manual_seed(8)
|
||||
image = pipeline(prompt, generator=generator).images[0]
|
||||
image
|
||||
```
|
||||
|
||||
<p align="center">
|
||||
<br>
|
||||
<img src="https://huggingface.co/datasets/patrickvonplaten/images/resolve/main/diffusers_docs/astronaut_ddim.png" width="400"/>
|
||||
<br>
|
||||
</p>
|
||||
|
||||
|
||||
|
||||
|
||||
## 스케줄러들 비교해보기
|
||||
|
||||
지금까지는 [`PNDMScheduler`]와 [`DDIMScheduler`] 스케줄러를 실행해보았습니다. 아직 비교해볼 스케줄러들이 더 많이 남아있으니 계속 비교해보도록 하겠습니다.
|
||||
|
||||
|
||||
|
||||
[`LMSDiscreteScheduler`]을 일반적으로 더 좋은 결과를 보여줍니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import LMSDiscreteScheduler
|
||||
|
||||
pipeline.scheduler = LMSDiscreteScheduler.from_config(pipeline.scheduler.config)
|
||||
|
||||
generator = torch.Generator(device="cuda").manual_seed(8)
|
||||
image = pipeline(prompt, generator=generator).images[0]
|
||||
image
|
||||
```
|
||||
|
||||
<p align="center">
|
||||
<br>
|
||||
<img src="https://huggingface.co/datasets/patrickvonplaten/images/resolve/main/diffusers_docs/astronaut_lms.png" width="400"/>
|
||||
<br>
|
||||
</p>
|
||||
|
||||
|
||||
[`EulerDiscreteScheduler`]와 [`EulerAncestralDiscreteScheduler`] 고작 30번의 inference step만으로도 높은 퀄리티의 이미지를 생성하는 것을 알 수 있습니다.
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import EulerDiscreteScheduler
|
||||
|
||||
pipeline.scheduler = EulerDiscreteScheduler.from_config(pipeline.scheduler.config)
|
||||
|
||||
generator = torch.Generator(device="cuda").manual_seed(8)
|
||||
image = pipeline(prompt, generator=generator, num_inference_steps=30).images[0]
|
||||
image
|
||||
```
|
||||
|
||||
<p align="center">
|
||||
<br>
|
||||
<img src="https://huggingface.co/datasets/patrickvonplaten/images/resolve/main/diffusers_docs/astronaut_euler_discrete.png" width="400"/>
|
||||
<br>
|
||||
</p>
|
||||
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import EulerAncestralDiscreteScheduler
|
||||
|
||||
pipeline.scheduler = EulerAncestralDiscreteScheduler.from_config(pipeline.scheduler.config)
|
||||
|
||||
generator = torch.Generator(device="cuda").manual_seed(8)
|
||||
image = pipeline(prompt, generator=generator, num_inference_steps=30).images[0]
|
||||
image
|
||||
```
|
||||
|
||||
<p align="center">
|
||||
<br>
|
||||
<img src="https://huggingface.co/datasets/patrickvonplaten/images/resolve/main/diffusers_docs/astronaut_euler_ancestral.png" width="400"/>
|
||||
<br>
|
||||
</p>
|
||||
|
||||
|
||||
지금 이 문서를 작성하는 현시점 기준에선, [`DPMSolverMultistepScheduler`]가 시간 대비 가장 좋은 품질의 이미지를 생성하는 것 같습니다. 20번 정도의 스텝만으로도 실행될 수 있습니다.
|
||||
|
||||
|
||||
|
||||
```python
|
||||
from MuseVdiffusers import DPMSolverMultistepScheduler
|
||||
|
||||
pipeline.scheduler = DPMSolverMultistepScheduler.from_config(pipeline.scheduler.config)
|
||||
|
||||
generator = torch.Generator(device="cuda").manual_seed(8)
|
||||
image = pipeline(prompt, generator=generator, num_inference_steps=20).images[0]
|
||||
image
|
||||
```
|
||||
|
||||
<p align="center">
|
||||
<br>
|
||||
<img src="https://huggingface.co/datasets/patrickvonplaten/images/resolve/main/diffusers_docs/astronaut_dpm.png" width="400"/>
|
||||
<br>
|
||||
</p>
|
||||
|
||||
|
||||
보시다시피 생성된 이미지들은 매우 비슷하고, 비슷한 퀄리티를 보이는 것 같습니다. 실제로 어떤 스케줄러를 선택할 것인가는 종종 특정 이용 사례에 기반해서 결정되곤 합니다. 결국 여러 종류의 스케줄러를 직접 실행시켜보고 눈으로 직접 비교해서 판단하는 게 좋은 선택일 것 같습니다.
|
||||
|
||||
|
||||
|
||||
## Flax에서 스케줄러 교체하기
|
||||
|
||||
JAX/Flax 사용자인 경우 기본 파이프라인 스케줄러를 변경할 수도 있습니다. 다음은 Flax Stable Diffusion 파이프라인과 초고속 [DDPM-Solver++ 스케줄러를](../api/schedulers/multistep_dpm_solver) 사용하여 추론을 실행하는 방법에 대한 예시입니다 .
|
||||
|
||||
```Python
|
||||
import jax
|
||||
import numpy as np
|
||||
from flax.jax_utils import replicate
|
||||
from flax.training.common_utils import shard
|
||||
|
||||
from MuseVdiffusers import FlaxStableDiffusionPipeline, FlaxDPMSolverMultistepScheduler
|
||||
|
||||
model_id = "runwayml/stable-diffusion-v1-5"
|
||||
scheduler, scheduler_state = FlaxDPMSolverMultistepScheduler.from_pretrained(
|
||||
model_id,
|
||||
subfolder="scheduler"
|
||||
)
|
||||
pipeline, params = FlaxStableDiffusionPipeline.from_pretrained(
|
||||
model_id,
|
||||
scheduler=scheduler,
|
||||
revision="bf16",
|
||||
dtype=jax.numpy.bfloat16,
|
||||
)
|
||||
params["scheduler"] = scheduler_state
|
||||
|
||||
# Generate 1 image per parallel device (8 on TPUv2-8 or TPUv3-8)
|
||||
prompt = "a photo of an astronaut riding a horse on mars"
|
||||
num_samples = jax.device_count()
|
||||
prompt_ids = pipeline.prepare_inputs([prompt] * num_samples)
|
||||
|
||||
prng_seed = jax.random.PRNGKey(0)
|
||||
num_inference_steps = 25
|
||||
|
||||
# shard inputs and rng
|
||||
params = replicate(params)
|
||||
prng_seed = jax.random.split(prng_seed, jax.device_count())
|
||||
prompt_ids = shard(prompt_ids)
|
||||
|
||||
images = pipeline(prompt_ids, params, prng_seed, num_inference_steps, jit=True).images
|
||||
images = pipeline.numpy_to_pil(np.asarray(images.reshape((num_samples,) + images.shape[-3:])))
|
||||
```
|
||||
|
||||
<Tip warning={true}>
|
||||
|
||||
다음 Flax 스케줄러는 *아직* Flax Stable Diffusion 파이프라인과 호환되지 않습니다.
|
||||
|
||||
- `FlaxLMSDiscreteScheduler`
|
||||
- `FlaxDDPMScheduler`
|
||||
|
||||
</Tip>
|
||||
|
||||
@@ -0,0 +1,264 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# JAX / Flax에서의 🧨 Stable Diffusion!
|
||||
|
||||
[[open-in-colab]]
|
||||
|
||||
🤗 Hugging Face [Diffusers] (https://github.com/huggingface/diffusers) 는 버전 0.5.1부터 Flax를 지원합니다! 이를 통해 Colab, Kaggle, Google Cloud Platform에서 사용할 수 있는 것처럼 Google TPU에서 초고속 추론이 가능합니다.
|
||||
|
||||
이 노트북은 JAX / Flax를 사용해 추론을 실행하는 방법을 보여줍니다. Stable Diffusion의 작동 방식에 대한 자세한 내용을 원하거나 GPU에서 실행하려면 이 [노트북] ](https://huggingface.co/docs/diffusers/stable_diffusion)을 참조하세요.
|
||||
|
||||
먼저, TPU 백엔드를 사용하고 있는지 확인합니다. Colab에서 이 노트북을 실행하는 경우, 메뉴에서 런타임을 선택한 다음 "런타임 유형 변경" 옵션을 선택한 다음 하드웨어 가속기 설정에서 TPU를 선택합니다.
|
||||
|
||||
JAX는 TPU 전용은 아니지만 각 TPU 서버에는 8개의 TPU 가속기가 병렬로 작동하기 때문에 해당 하드웨어에서 더 빛을 발한다는 점은 알아두세요.
|
||||
|
||||
|
||||
## Setup
|
||||
|
||||
먼저 diffusers가 설치되어 있는지 확인합니다.
|
||||
|
||||
```bash
|
||||
!pip install jax==0.3.25 jaxlib==0.3.25 flax transformers ftfy
|
||||
!pip install diffusers
|
||||
```
|
||||
|
||||
```python
|
||||
import jax.tools.colab_tpu
|
||||
|
||||
jax.tools.colab_tpu.setup_tpu()
|
||||
import jax
|
||||
```
|
||||
|
||||
```python
|
||||
num_devices = jax.device_count()
|
||||
device_type = jax.devices()[0].device_kind
|
||||
|
||||
print(f"Found {num_devices} JAX devices of type {device_type}.")
|
||||
assert (
|
||||
"TPU" in device_type
|
||||
), "Available device is not a TPU, please select TPU from Edit > Notebook settings > Hardware accelerator"
|
||||
```
|
||||
|
||||
```python out
|
||||
Found 8 JAX devices of type Cloud TPU.
|
||||
```
|
||||
|
||||
그런 다음 모든 dependencies를 가져옵니다.
|
||||
|
||||
```python
|
||||
import numpy as np
|
||||
import jax
|
||||
import jax.numpy as jnp
|
||||
|
||||
from pathlib import Path
|
||||
from jax import pmap
|
||||
from flax.jax_utils import replicate
|
||||
from flax.training.common_utils import shard
|
||||
from PIL import Image
|
||||
|
||||
from huggingface_hub import notebook_login
|
||||
from MuseVdiffusers import FlaxStableDiffusionPipeline
|
||||
```
|
||||
|
||||
## 모델 불러오기
|
||||
|
||||
TPU 장치는 효율적인 half-float 유형인 bfloat16을 지원합니다. 테스트에는 이 유형을 사용하지만 대신 float32를 사용하여 전체 정밀도(full precision)를 사용할 수도 있습니다.
|
||||
|
||||
```python
|
||||
dtype = jnp.bfloat16
|
||||
```
|
||||
|
||||
Flax는 함수형 프레임워크이므로 모델은 무상태(stateless)형이며 매개변수는 모델 외부에 저장됩니다. 사전학습된 Flax 파이프라인을 불러오면 파이프라인 자체와 모델 가중치(또는 매개변수)가 모두 반환됩니다. 저희는 bf16 버전의 가중치를 사용하고 있으므로 유형 경고가 표시되지만 무시해도 됩니다.
|
||||
|
||||
```python
|
||||
pipeline, params = FlaxStableDiffusionPipeline.from_pretrained(
|
||||
"CompVis/stable-diffusion-v1-4",
|
||||
revision="bf16",
|
||||
dtype=dtype,
|
||||
)
|
||||
```
|
||||
|
||||
## 추론
|
||||
|
||||
TPU에는 일반적으로 8개의 디바이스가 병렬로 작동하므로 보유한 디바이스 수만큼 프롬프트를 복제합니다. 그런 다음 각각 하나의 이미지 생성을 담당하는 8개의 디바이스에서 한 번에 추론을 수행합니다. 따라서 하나의 칩이 하나의 이미지를 생성하는 데 걸리는 시간과 동일한 시간에 8개의 이미지를 얻을 수 있습니다.
|
||||
|
||||
프롬프트를 복제하고 나면 파이프라인의 `prepare_inputs` 함수를 호출하여 토큰화된 텍스트 ID를 얻습니다. 토큰화된 텍스트의 길이는 기본 CLIP 텍스트 모델의 구성에 따라 77토큰으로 설정됩니다.
|
||||
|
||||
```python
|
||||
prompt = "A cinematic film still of Morgan Freeman starring as Jimi Hendrix, portrait, 40mm lens, shallow depth of field, close up, split lighting, cinematic"
|
||||
prompt = [prompt] * jax.device_count()
|
||||
prompt_ids = pipeline.prepare_inputs(prompt)
|
||||
prompt_ids.shape
|
||||
```
|
||||
|
||||
```python out
|
||||
(8, 77)
|
||||
```
|
||||
|
||||
### 복사(Replication) 및 정렬화
|
||||
|
||||
모델 매개변수와 입력값은 우리가 보유한 8개의 병렬 장치에 복사(Replication)되어야 합니다. 매개변수 딕셔너리는 `flax.jax_utils.replicate`(딕셔너리를 순회하며 가중치의 모양을 변경하여 8번 반복하는 함수)를 사용하여 복사됩니다. 배열은 `shard`를 사용하여 복제됩니다.
|
||||
|
||||
```python
|
||||
p_params = replicate(params)
|
||||
```
|
||||
|
||||
```python
|
||||
prompt_ids = shard(prompt_ids)
|
||||
prompt_ids.shape
|
||||
```
|
||||
|
||||
```python out
|
||||
(8, 1, 77)
|
||||
```
|
||||
|
||||
이 shape은 8개의 디바이스 각각이 shape `(1, 77)`의 jnp 배열을 입력값으로 받는다는 의미입니다. 즉 1은 디바이스당 batch(배치) 크기입니다. 메모리가 충분한 TPU에서는 한 번에 여러 이미지(칩당)를 생성하려는 경우 1보다 클 수 있습니다.
|
||||
|
||||
이미지를 생성할 준비가 거의 완료되었습니다! 이제 생성 함수에 전달할 난수 생성기만 만들면 됩니다. 이것은 난수를 다루는 모든 함수에 난수 생성기가 있어야 한다는, 난수에 대해 매우 진지하고 독단적인 Flax의 표준 절차입니다. 이렇게 하면 여러 분산된 기기에서 훈련할 때에도 재현성이 보장됩니다.
|
||||
|
||||
아래 헬퍼 함수는 시드를 사용하여 난수 생성기를 초기화합니다. 동일한 시드를 사용하는 한 정확히 동일한 결과를 얻을 수 있습니다. 나중에 노트북에서 결과를 탐색할 때엔 다른 시드를 자유롭게 사용하세요.
|
||||
|
||||
```python
|
||||
def create_key(seed=0):
|
||||
return jax.random.PRNGKey(seed)
|
||||
```
|
||||
|
||||
rng를 얻은 다음 8번 '분할'하여 각 디바이스가 다른 제너레이터를 수신하도록 합니다. 따라서 각 디바이스마다 다른 이미지가 생성되며 전체 프로세스를 재현할 수 있습니다.
|
||||
|
||||
```python
|
||||
rng = create_key(0)
|
||||
rng = jax.random.split(rng, jax.device_count())
|
||||
```
|
||||
|
||||
JAX 코드는 매우 빠르게 실행되는 효율적인 표현으로 컴파일할 수 있습니다. 하지만 후속 호출에서 모든 입력이 동일한 모양을 갖도록 해야 하며, 그렇지 않으면 JAX가 코드를 다시 컴파일해야 하므로 최적화된 속도를 활용할 수 없습니다.
|
||||
|
||||
`jit = True`를 인수로 전달하면 Flax 파이프라인이 코드를 컴파일할 수 있습니다. 또한 모델이 사용 가능한 8개의 디바이스에서 병렬로 실행되도록 보장합니다.
|
||||
|
||||
다음 셀을 처음 실행하면 컴파일하는 데 시간이 오래 걸리지만 이후 호출(입력이 다른 경우에도)은 훨씬 빨라집니다. 예를 들어, 테스트했을 때 TPU v2-8에서 컴파일하는 데 1분 이상 걸리지만 이후 추론 실행에는 약 7초가 걸립니다.
|
||||
|
||||
```
|
||||
%%time
|
||||
images = pipeline(prompt_ids, p_params, rng, jit=True)[0]
|
||||
```
|
||||
|
||||
```python out
|
||||
CPU times: user 56.2 s, sys: 42.5 s, total: 1min 38s
|
||||
Wall time: 1min 29s
|
||||
```
|
||||
|
||||
반환된 배열의 shape은 `(8, 1, 512, 512, 3)`입니다. 이를 재구성하여 두 번째 차원을 제거하고 512 × 512 × 3의 이미지 8개를 얻은 다음 PIL로 변환합니다.
|
||||
|
||||
```python
|
||||
images = images.reshape((images.shape[0] * images.shape[1],) + images.shape[-3:])
|
||||
images = pipeline.numpy_to_pil(images)
|
||||
```
|
||||
|
||||
### 시각화
|
||||
|
||||
이미지를 그리드에 표시하는 도우미 함수를 만들어 보겠습니다.
|
||||
|
||||
```python
|
||||
def image_grid(imgs, rows, cols):
|
||||
w, h = imgs[0].size
|
||||
grid = Image.new("RGB", size=(cols * w, rows * h))
|
||||
for i, img in enumerate(imgs):
|
||||
grid.paste(img, box=(i % cols * w, i // cols * h))
|
||||
return grid
|
||||
```
|
||||
|
||||
```python
|
||||
image_grid(images, 2, 4)
|
||||
```
|
||||
|
||||
|
||||
|
||||
|
||||
## 다른 프롬프트 사용
|
||||
|
||||
모든 디바이스에서 동일한 프롬프트를 복제할 필요는 없습니다. 프롬프트 2개를 각각 4번씩 생성하거나 한 번에 8개의 서로 다른 프롬프트를 생성하는 등 원하는 것은 무엇이든 할 수 있습니다. 한번 해보세요!
|
||||
|
||||
먼저 입력 준비 코드를 편리한 함수로 리팩터링하겠습니다:
|
||||
|
||||
```python
|
||||
prompts = [
|
||||
"Labrador in the style of Hokusai",
|
||||
"Painting of a squirrel skating in New York",
|
||||
"HAL-9000 in the style of Van Gogh",
|
||||
"Times Square under water, with fish and a dolphin swimming around",
|
||||
"Ancient Roman fresco showing a man working on his laptop",
|
||||
"Close-up photograph of young black woman against urban background, high quality, bokeh",
|
||||
"Armchair in the shape of an avocado",
|
||||
"Clown astronaut in space, with Earth in the background",
|
||||
]
|
||||
```
|
||||
|
||||
```python
|
||||
prompt_ids = pipeline.prepare_inputs(prompts)
|
||||
prompt_ids = shard(prompt_ids)
|
||||
|
||||
images = pipeline(prompt_ids, p_params, rng, jit=True).images
|
||||
images = images.reshape((images.shape[0] * images.shape[1],) + images.shape[-3:])
|
||||
images = pipeline.numpy_to_pil(images)
|
||||
|
||||
image_grid(images, 2, 4)
|
||||
```
|
||||
|
||||
|
||||
|
||||
|
||||
## 병렬화(parallelization)는 어떻게 작동하는가?
|
||||
|
||||
앞서 `diffusers` Flax 파이프라인이 모델을 자동으로 컴파일하고 사용 가능한 모든 기기에서 병렬로 실행한다고 말씀드렸습니다. 이제 그 프로세스를 간략하게 살펴보고 작동 방식을 보여드리겠습니다.
|
||||
|
||||
JAX 병렬화는 여러 가지 방법으로 수행할 수 있습니다. 가장 쉬운 방법은 jax.pmap 함수를 사용하여 단일 프로그램, 다중 데이터(SPMD) 병렬화를 달성하는 것입니다. 즉, 동일한 코드의 복사본을 각각 다른 데이터 입력에 대해 여러 개 실행하는 것입니다. 더 정교한 접근 방식도 가능하므로 관심이 있으시다면 [JAX 문서](https://jax.readthedocs.io/en/latest/index.html)와 [`pjit` 페이지](https://jax.readthedocs.io/en/latest/jax-101/08-pjit.html?highlight=pjit)에서 이 주제를 살펴보시기 바랍니다!
|
||||
|
||||
`jax.pmap`은 두 가지 기능을 수행합니다:
|
||||
|
||||
- `jax.jit()`를 호출한 것처럼 코드를 컴파일(또는 `jit`)합니다. 이 작업은 `pmap`을 호출할 때가 아니라 pmapped 함수가 처음 호출될 때 수행됩니다.
|
||||
- 컴파일된 코드가 사용 가능한 모든 기기에서 병렬로 실행되도록 합니다.
|
||||
|
||||
작동 방식을 보여드리기 위해 이미지 생성을 실행하는 비공개 메서드인 파이프라인의 `_generate` 메서드를 `pmap`합니다. 이 메서드는 향후 `Diffusers` 릴리스에서 이름이 변경되거나 제거될 수 있다는 점에 유의하세요.
|
||||
|
||||
```python
|
||||
p_generate = pmap(pipeline._generate)
|
||||
```
|
||||
|
||||
`pmap`을 사용한 후 준비된 함수 `p_generate`는 개념적으로 다음을 수행합니다:
|
||||
* 각 장치에서 기본 함수 `pipeline._generate`의 복사본을 호출합니다.
|
||||
* 각 장치에 입력 인수의 다른 부분을 보냅니다. 이것이 바로 샤딩이 사용되는 이유입니다. 이 경우 `prompt_ids`의 shape은 `(8, 1, 77, 768)`입니다. 이 배열은 8개로 분할되고 `_generate`의 각 복사본은 `(1, 77, 768)`의 shape을 가진 입력을 받게 됩니다.
|
||||
|
||||
병렬로 호출된다는 사실을 완전히 무시하고 `_generate`를 코딩할 수 있습니다. batch(배치) 크기(이 예제에서는 `1`)와 코드에 적합한 차원만 신경 쓰면 되며, 병렬로 작동하기 위해 아무것도 변경할 필요가 없습니다.
|
||||
|
||||
파이프라인 호출을 사용할 때와 마찬가지로, 다음 셀을 처음 실행할 때는 시간이 걸리지만 그 이후에는 훨씬 빨라집니다.
|
||||
|
||||
```
|
||||
%%time
|
||||
images = p_generate(prompt_ids, p_params, rng)
|
||||
images = images.block_until_ready()
|
||||
images.shape
|
||||
```
|
||||
|
||||
```python out
|
||||
CPU times: user 1min 15s, sys: 18.2 s, total: 1min 34s
|
||||
Wall time: 1min 15s
|
||||
```
|
||||
|
||||
```python
|
||||
images.shape
|
||||
```
|
||||
|
||||
```python out
|
||||
(8, 1, 512, 512, 3)
|
||||
```
|
||||
|
||||
JAX는 비동기 디스패치를 사용하고 가능한 한 빨리 제어권을 Python 루프에 반환하기 때문에 추론 시간을 정확하게 측정하기 위해 `block_until_ready()`를 사용합니다. 아직 구체화되지 않은 계산 결과를 사용하려는 경우 자동으로 차단이 수행되므로 코드에서 이 함수를 사용할 필요가 없습니다.
|
||||
@@ -0,0 +1,80 @@
|
||||
# Textual inversion
|
||||
|
||||
[[open-in-colab]]
|
||||
|
||||
[`StableDiffusionPipeline`]은 textual-inversion을 지원하는데, 이는 몇 개의 샘플 이미지만으로 stable diffusion과 같은 모델이 새로운 컨셉을 학습할 수 있도록 하는 기법입니다. 이를 통해 생성된 이미지를 더 잘 제어하고 특정 컨셉에 맞게 모델을 조정할 수 있습니다. 커뮤니티에서 만들어진 컨셉들의 컬렉션은 [Stable Diffusion Conceptualizer](https://huggingface.co/spaces/sd-concepts-library/stable-diffusion-conceptualizer)를 통해 빠르게 사용해볼 수 있습니다.
|
||||
|
||||
이 가이드에서는 Stable Diffusion Conceptualizer에서 사전학습한 컨셉을 사용하여 textual-inversion으로 추론을 실행하는 방법을 보여드립니다. textual-inversion으로 모델에 새로운 컨셉을 학습시키는 데 관심이 있으시다면, [Textual Inversion](./training/text_inversion) 훈련 가이드를 참조하세요.
|
||||
|
||||
Hugging Face 계정으로 로그인하세요:
|
||||
|
||||
```py
|
||||
from huggingface_hub import notebook_login
|
||||
|
||||
notebook_login()
|
||||
```
|
||||
|
||||
필요한 라이브러리를 불러오고 생성된 이미지를 시각화하기 위한 도우미 함수 `image_grid`를 만듭니다:
|
||||
|
||||
```py
|
||||
import os
|
||||
import torch
|
||||
|
||||
import PIL
|
||||
from PIL import Image
|
||||
|
||||
from MuseVdiffusers import StableDiffusionPipeline
|
||||
from transformers import CLIPFeatureExtractor, CLIPTextModel, CLIPTokenizer
|
||||
|
||||
|
||||
def image_grid(imgs, rows, cols):
|
||||
assert len(imgs) == rows * cols
|
||||
|
||||
w, h = imgs[0].size
|
||||
grid = Image.new("RGB", size=(cols * w, rows * h))
|
||||
grid_w, grid_h = grid.size
|
||||
|
||||
for i, img in enumerate(imgs):
|
||||
grid.paste(img, box=(i % cols * w, i // cols * h))
|
||||
return grid
|
||||
```
|
||||
|
||||
Stable Diffusion과 [Stable Diffusion Conceptualizer](https://huggingface.co/spaces/sd-concepts-library/stable-diffusion-conceptualizer)에서 사전학습된 컨셉을 선택합니다:
|
||||
|
||||
```py
|
||||
pretrained_model_name_or_path = "runwayml/stable-diffusion-v1-5"
|
||||
repo_id_embeds = "sd-concepts-library/cat-toy"
|
||||
```
|
||||
|
||||
이제 파이프라인을 로드하고 사전학습된 컨셉을 파이프라인에 전달할 수 있습니다:
|
||||
|
||||
```py
|
||||
pipeline = StableDiffusionPipeline.from_pretrained(pretrained_model_name_or_path, torch_dtype=torch.float16).to("cuda")
|
||||
|
||||
pipeline.load_textual_inversion(repo_id_embeds)
|
||||
```
|
||||
|
||||
특별한 placeholder token '`<cat-toy>`'를 사용하여 사전학습된 컨셉으로 프롬프트를 만들고, 생성할 샘플의 수와 이미지 행의 수를 선택합니다:
|
||||
|
||||
```py
|
||||
prompt = "a grafitti in a favela wall with a <cat-toy> on it"
|
||||
|
||||
num_samples = 2
|
||||
num_rows = 2
|
||||
```
|
||||
|
||||
그런 다음 파이프라인을 실행하고, 생성된 이미지들을 저장합니다. 그리고 처음에 만들었던 도우미 함수 `image_grid`를 사용하여 생성 결과들을 시각화합니다. 이 때 `num_inference_steps`와 `guidance_scale`과 같은 매개 변수들을 조정하여, 이것들이 이미지 품질에 어떠한 영향을 미치는지를 자유롭게 확인해보시기 바랍니다.
|
||||
|
||||
```py
|
||||
all_images = []
|
||||
for _ in range(num_rows):
|
||||
images = pipe(prompt, num_images_per_prompt=num_samples, num_inference_steps=50, guidance_scale=7.5).images
|
||||
all_images.extend(images)
|
||||
|
||||
grid = image_grid(all_images, num_samples, num_rows)
|
||||
grid
|
||||
```
|
||||
|
||||
<div class="flex justify-center">
|
||||
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/textual_inversion_inference.png">
|
||||
</div>
|
||||
@@ -0,0 +1,60 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# Unconditional 이미지 생성
|
||||
|
||||
[[open-in-colab]]
|
||||
|
||||
Unconditional 이미지 생성은 비교적 간단한 작업입니다. 모델이 텍스트나 이미지와 같은 추가 조건 없이 이미 학습된 학습 데이터와 유사한 이미지만 생성합니다.
|
||||
|
||||
['DiffusionPipeline']은 추론을 위해 미리 학습된 diffusion 시스템을 사용하는 가장 쉬운 방법입니다.
|
||||
|
||||
먼저 ['DiffusionPipeline']의 인스턴스를 생성하고 다운로드할 파이프라인의 [체크포인트](https://huggingface.co/models?library=diffusers&sort=downloads)를 지정합니다. 허브의 🧨 diffusion 체크포인트 중 하나를 사용할 수 있습니다(사용할 체크포인트는 나비 이미지를 생성합니다).
|
||||
|
||||
<Tip>
|
||||
|
||||
💡 나만의 unconditional 이미지 생성 모델을 학습시키고 싶으신가요? 학습 가이드를 살펴보고 나만의 이미지를 생성하는 방법을 알아보세요.
|
||||
|
||||
</Tip>
|
||||
|
||||
|
||||
이 가이드에서는 unconditional 이미지 생성에 ['DiffusionPipeline']과 [DDPM](https://arxiv.org/abs/2006.11239)을 사용합니다:
|
||||
|
||||
```python
|
||||
>>> from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
>>> generator = DiffusionPipeline.from_pretrained("anton-l/ddpm-butterflies-128")
|
||||
```
|
||||
|
||||
[diffusion 파이프라인]은 모든 모델링, 토큰화, 스케줄링 구성 요소를 다운로드하고 캐시합니다. 이 모델은 약 14억 개의 파라미터로 구성되어 있기 때문에 GPU에서 실행할 것을 강력히 권장합니다. PyTorch에서와 마찬가지로 제너레이터 객체를 GPU로 옮길 수 있습니다:
|
||||
|
||||
```python
|
||||
>>> generator.to("cuda")
|
||||
```
|
||||
|
||||
이제 제너레이터를 사용하여 이미지를 생성할 수 있습니다:
|
||||
|
||||
```python
|
||||
>>> image = generator().images[0]
|
||||
```
|
||||
|
||||
출력은 기본적으로 [PIL.Image](https://pillow.readthedocs.io/en/stable/reference/Image.html?highlight=image#the-image-class) 객체로 감싸집니다.
|
||||
|
||||
다음을 호출하여 이미지를 저장할 수 있습니다:
|
||||
|
||||
```python
|
||||
>>> image.save("generated_image.png")
|
||||
```
|
||||
|
||||
아래 스페이스(데모 링크)를 이용해 보고, 추론 단계의 매개변수를 자유롭게 조절하여 이미지 품질에 어떤 영향을 미치는지 확인해 보세요!
|
||||
|
||||
<iframe src="https://stevhliu-ddpm-butterflies-128.hf.space" frameborder="0" width="850" height="500"></iframe>
|
||||
@@ -0,0 +1,67 @@
|
||||
# 세이프텐서 로드
|
||||
|
||||
[safetensors](https://github.com/huggingface/safetensors)는 텐서를 저장하고 로드하기 위한 안전하고 빠른 파일 형식입니다. 일반적으로 PyTorch 모델 가중치는 Python의 [`pickle`](https://docs.python.org/3/library/pickle.html) 유틸리티를 사용하여 `.bin` 파일에 저장되거나 `피클`됩니다. 그러나 `피클`은 안전하지 않으며 피클된 파일에는 실행될 수 있는 악성 코드가 포함될 수 있습니다. 세이프텐서는 `피클`의 안전한 대안으로 모델 가중치를 공유하는 데 이상적입니다.
|
||||
|
||||
이 가이드에서는 `.safetensor` 파일을 로드하는 방법과 다른 형식으로 저장된 안정적 확산 모델 가중치를 `.safetensor`로 변환하는 방법을 보여드리겠습니다. 시작하기 전에 세이프텐서가 설치되어 있는지 확인하세요:
|
||||
|
||||
```bash
|
||||
!pip install safetensors
|
||||
```
|
||||
|
||||
['runwayml/stable-diffusion-v1-5`] (https://huggingface.co/runwayml/stable-diffusion-v1-5/tree/main) 리포지토리를 보면 `text_encoder`, `unet` 및 `vae` 하위 폴더에 가중치가 `.safetensors` 형식으로 저장되어 있는 것을 볼 수 있습니다. 기본적으로 🤗 디퓨저는 모델 저장소에서 사용할 수 있는 경우 해당 하위 폴더에서 이러한 '.safetensors` 파일을 자동으로 로드합니다.
|
||||
|
||||
보다 명시적인 제어를 위해 선택적으로 `사용_세이프텐서=True`를 설정할 수 있습니다(`세이프텐서`가 설치되지 않은 경우 설치하라는 오류 메시지가 표시됨):
|
||||
|
||||
```py
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
pipeline = DiffusionPipeline.from_pretrained("runwayml/stable-diffusion-v1-5", use_safetensors=True)
|
||||
```
|
||||
|
||||
그러나 모델 가중치가 위의 예시처럼 반드시 별도의 하위 폴더에 저장되는 것은 아닙니다. 모든 가중치가 하나의 '.safetensors` 파일에 저장되는 경우도 있습니다. 이 경우 가중치가 Stable Diffusion 가중치인 경우 [`~diffusers.loaders.FromCkptMixin.from_ckpt`] 메서드를 사용하여 파일을 직접 로드할 수 있습니다:
|
||||
|
||||
```py
|
||||
from MuseVdiffusers import StableDiffusionPipeline
|
||||
|
||||
pipeline = StableDiffusionPipeline.from_ckpt(
|
||||
"https://huggingface.co/WarriorMama777/OrangeMixs/blob/main/Models/AbyssOrangeMix/AbyssOrangeMix.safetensors"
|
||||
)
|
||||
```
|
||||
|
||||
## 세이프텐서로 변환
|
||||
|
||||
허브의 모든 가중치를 '.safetensors` 형식으로 사용할 수 있는 것은 아니며, '.bin`으로 저장된 가중치가 있을 수 있습니다. 이 경우 [Convert Space](https://huggingface.co/spaces/diffusers/convert)을 사용하여 가중치를 '.safetensors'로 변환하세요. Convert Space는 피클된 가중치를 다운로드하여 변환한 후 풀 리퀘스트를 열어 허브에 새로 변환된 `.safetensors` 파일을 업로드합니다. 이렇게 하면 피클된 파일에 악성 코드가 포함되어 있는 경우, 안전하지 않은 파일과 의심스러운 피클 가져오기를 탐지하는 [보안 스캐너](https://huggingface.co/docs/hub/security-pickle#hubs-security-scanner)가 있는 허브로 업로드됩니다. - 개별 컴퓨터가 아닌.
|
||||
|
||||
개정` 매개변수에 풀 리퀘스트에 대한 참조를 지정하여 새로운 '.safetensors` 가중치가 적용된 모델을 사용할 수 있습니다(허브의 [Check PR](https://huggingface.co/spaces/diffusers/check_pr) 공간에서 테스트할 수도 있음)(예: `refs/pr/22`):
|
||||
|
||||
```py
|
||||
from MuseVdiffusers import DiffusionPipeline
|
||||
|
||||
pipeline = DiffusionPipeline.from_pretrained("stabilityai/stable-diffusion-2-1", revision="refs/pr/22")
|
||||
```
|
||||
|
||||
## 세이프센서를 사용하는 이유는 무엇인가요?
|
||||
|
||||
세이프티 센서를 사용하는 데에는 여러 가지 이유가 있습니다:
|
||||
|
||||
- 세이프텐서를 사용하는 가장 큰 이유는 안전입니다.오픈 소스 및 모델 배포가 증가함에 따라 다운로드한 모델 가중치에 악성 코드가 포함되어 있지 않다는 것을 신뢰할 수 있는 것이 중요해졌습니다.세이프센서의 현재 헤더 크기는 매우 큰 JSON 파일을 구문 분석하지 못하게 합니다.
|
||||
- 모델 전환 간의 로딩 속도는 텐서의 제로 카피를 수행하는 세이프텐서를 사용해야 하는 또 다른 이유입니다. 가중치를 CPU(기본값)로 로드하는 경우 '피클'에 비해 특히 빠르며, 가중치를 GPU로 직접 로드하는 경우에도 빠르지는 않더라도 비슷하게 빠릅니다. 모델이 이미 로드된 경우에만 성능 차이를 느낄 수 있으며, 가중치를 다운로드하거나 모델을 처음 로드하는 경우에는 성능 차이를 느끼지 못할 것입니다.
|
||||
|
||||
전체 파이프라인을 로드하는 데 걸리는 시간입니다:
|
||||
|
||||
```py
|
||||
from MuseVdiffusers import StableDiffusionPipeline
|
||||
|
||||
pipeline = StableDiffusionPipeline.from_pretrained("stabilityai/stable-diffusion-2-1")
|
||||
"Loaded in safetensors 0:00:02.033658"
|
||||
"Loaded in PyTorch 0:00:02.663379"
|
||||
```
|
||||
|
||||
하지만 실제로 500MB의 모델 가중치를 로드하는 데 걸리는 시간은 얼마 되지 않습니다:
|
||||
|
||||
```bash
|
||||
safetensors: 3.4873ms
|
||||
PyTorch: 172.7537ms
|
||||
```
|
||||
|
||||
지연 로딩은 세이프텐서에서도 지원되며, 이는 분산 설정에서 일부 텐서만 로드하는 데 유용합니다. 이 형식을 사용하면 [BLOOM](https://huggingface.co/bigscience/bloom) 모델을 일반 PyTorch 가중치를 사용하여 10분이 걸리던 것을 8개의 GPU에서 45초 만에 로드할 수 있습니다.
|
||||
@@ -0,0 +1,115 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# 프롬프트에 가중치 부여하기
|
||||
|
||||
[[open-in-colab]]
|
||||
|
||||
텍스트 가이드 기반의 diffusion 모델은 주어진 텍스트 프롬프트를 기반으로 이미지를 생성합니다.
|
||||
텍스트 프롬프트에는 모델이 생성해야 하는 여러 개념이 포함될 수 있으며 프롬프트의 특정 부분에 가중치를 부여하는 것이 바람직한 경우가 많습니다.
|
||||
|
||||
Diffusion 모델은 문맥화된 텍스트 임베딩으로 diffusion 모델의 cross attention 레이어를 조절함으로써 작동합니다.
|
||||
([더 많은 정보를 위한 Stable Diffusion Guide](https://huggingface.co/docs/optimum-neuron/main/en/package_reference/modeling#stable-diffusion)를 참고하세요).
|
||||
따라서 프롬프트의 특정 부분을 강조하는(또는 강조하지 않는) 간단한 방법은 프롬프트의 관련 부분에 해당하는 텍스트 임베딩 벡터의 크기를 늘리거나 줄이는 것입니다.
|
||||
이것은 "프롬프트 가중치 부여" 라고 하며, 커뮤니티에서 가장 요구하는 기능입니다.([이곳](https://github.com/huggingface/diffusers/issues/2431)의 issue를 보세요 ).
|
||||
|
||||
## Diffusers에서 프롬프트 가중치 부여하는 방법
|
||||
|
||||
우리는 `diffusers`의 역할이 다른 프로젝트를 가능하게 하는 필수적인 기능을 제공하는 toolbex라고 생각합니다.
|
||||
[InvokeAI](https://github.com/invoke-ai/InvokeAI) 나 [diffuzers](https://github.com/abhishekkrthakur/diffuzers) 같은 강력한 UI를 구축할 수 있습니다.
|
||||
프롬프트를 조작하는 방법을 지원하기 위해, `diffusers` 는
|
||||
[StableDiffusionPipeline](https://huggingface.co/docs/diffusers/v0.18.2/en/api/pipelines/stable_diffusion/text2img#diffusers.StableDiffusionPipeline)와 같은
|
||||
많은 파이프라인에 [prompt_embeds](https://huggingface.co/docs/diffusers/v0.14.0/en/api/pipelines/stable_diffusion/text2img#diffusers.StableDiffusionPipeline.__call__.prompt_embeds)
|
||||
인수를 노출시켜, "prompt-weighted"/축척된 텍스트 임베딩을 파이프라인에 바로 전달할 수 있게 합니다.
|
||||
|
||||
[Compel 라이브러리](https://github.com/damian0815/compel)는 프롬프트의 일부를 강조하거나 강조하지 않을 수 있는 쉬운 방법을 제공합니다.
|
||||
임베딩을 직접 준비하는 것 대신 이 방법을 사용하는 것을 강력히 추천합니다.
|
||||
|
||||
간단한 예제를 살펴보겠습니다.
|
||||
다음과 같이 `"공을 갖고 노는 붉은색 고양이"` 이미지를 생성하고 싶습니다:
|
||||
|
||||
```py
|
||||
from MuseVdiffusers import StableDiffusionPipeline, UniPCMultistepScheduler
|
||||
|
||||
pipe = StableDiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4")
|
||||
pipe.scheduler = UniPCMultistepScheduler.from_config(pipe.scheduler.config)
|
||||
|
||||
prompt = "a red cat playing with a ball"
|
||||
|
||||
generator = torch.Generator(device="cpu").manual_seed(33)
|
||||
|
||||
image = pipe(prompt, generator=generator, num_inference_steps=20).images[0]
|
||||
image
|
||||
```
|
||||
|
||||
생성된 이미지:
|
||||
|
||||
|
||||
|
||||
사진에서 알 수 있듯이, "공"은 이미지에 없습니다. 이 부분을 강조해 볼까요!
|
||||
|
||||
먼저 `compel` 라이브러리를 설치해야합니다:
|
||||
|
||||
```
|
||||
pip install compel
|
||||
```
|
||||
|
||||
그런 다음에는 `Compel` 오브젝트를 생성합니다:
|
||||
|
||||
```py
|
||||
from compel import Compel
|
||||
|
||||
compel_proc = Compel(tokenizer=pipe.tokenizer, text_encoder=pipe.text_encoder)
|
||||
```
|
||||
|
||||
이제 `"++"` 를 사용해서 "공" 을 강조해 봅시다:
|
||||
|
||||
```py
|
||||
prompt = "a red cat playing with a ball++"
|
||||
```
|
||||
|
||||
그리고 이 프롬프트를 파이프라인에 바로 전달하지 않고, `compel_proc` 를 사용하여 처리해야합니다:
|
||||
|
||||
```py
|
||||
prompt_embeds = compel_proc(prompt)
|
||||
```
|
||||
|
||||
파이프라인에 `prompt_embeds` 를 바로 전달할 수 있습니다:
|
||||
|
||||
```py
|
||||
generator = torch.Generator(device="cpu").manual_seed(33)
|
||||
|
||||
images = pipe(prompt_embeds=prompt_embeds, generator=generator, num_inference_steps=20).images[0]
|
||||
image
|
||||
```
|
||||
|
||||
이제 "공"이 있는 그림을 출력할 수 있습니다!
|
||||
|
||||

|
||||
|
||||
마찬가지로 `--` 접미사를 단어에 사용하여 문장의 일부를 강조하지 않을 수 있습니다. 한번 시도해 보세요!
|
||||
|
||||
즐겨찾는 파이프라인에 `prompt_embeds` 입력이 없는 경우 issue를 새로 만들어주세요.
|
||||
Diffusers 팀은 최대한 대응하려고 노력합니다.
|
||||
|
||||
Compel 1.1.6 는 textual inversions을 사용하여 단순화하는 유티릴티 클래스를 추가합니다.
|
||||
`DiffusersTextualInversionManager`를 인스턴스화 한 후 이를 Compel init에 전달합니다:
|
||||
|
||||
```
|
||||
textual_inversion_manager = DiffusersTextualInversionManager(pipe)
|
||||
compel = Compel(
|
||||
tokenizer=pipe.tokenizer,
|
||||
text_encoder=pipe.text_encoder,
|
||||
textual_inversion_manager=textual_inversion_manager)
|
||||
```
|
||||
|
||||
더 많은 정보를 얻고 싶다면 [compel](https://github.com/damian0815/compel) 라이브러리 문서를 참고하세요.
|
||||
@@ -0,0 +1,290 @@
|
||||
<!--Copyright 2023 The HuggingFace Team. All rights reserved.
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
||||
the License. You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
||||
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
||||
specific language governing permissions and limitations under the License.
|
||||
-->
|
||||
|
||||
# 파이프라인, 모델 및 스케줄러 이해하기
|
||||
|
||||
[[open-in-colab]]
|
||||
|
||||
🧨 Diffusers는 사용자 친화적이며 유연한 도구 상자로, 사용사례에 맞게 diffusion 시스템을 구축 할 수 있도록 설계되었습니다. 이 도구 상자의 핵심은 모델과 스케줄러입니다. [`DiffusionPipeline`]은 편의를 위해 이러한 구성 요소를 번들로 제공하지만, 파이프라인을 분리하고 모델과 스케줄러를 개별적으로 사용해 새로운 diffusion 시스템을 만들 수도 있습니다.
|
||||
|
||||
이 튜토리얼에서는 기본 파이프라인부터 시작해 Stable Diffusion 파이프라인까지 진행하며 모델과 스케줄러를 사용해 추론을 위한 diffusion 시스템을 조립하는 방법을 배웁니다.
|
||||
|
||||
## 기본 파이프라인 해체하기
|
||||
|
||||
파이프라인은 추론을 위해 모델을 실행하는 빠르고 쉬운 방법으로, 이미지를 생성하는 데 코드가 4줄 이상 필요하지 않습니다:
|
||||
|
||||
```py
|
||||
>>> from MuseVdiffusers import DDPMPipeline
|
||||
|
||||
>>> ddpm = DDPMPipeline.from_pretrained("google/ddpm-cat-256").to("cuda")
|
||||
>>> image = ddpm(num_inference_steps=25).images[0]
|
||||
>>> image
|
||||
```
|
||||
|
||||
<div class="flex justify-center">
|
||||
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/ddpm-cat.png" alt="Image of cat created from DDPMPipeline"/>
|
||||
</div>
|
||||
|
||||
정말 쉽습니다. 그런데 파이프라인은 어떻게 이렇게 할 수 있었을까요? 파이프라인을 세분화하여 내부에서 어떤 일이 일어나고 있는지 살펴보겠습니다.
|
||||
|
||||
위 예시에서 파이프라인에는 [`UNet2DModel`] 모델과 [`DDPMScheduler`]가 포함되어 있습니다. 파이프라인은 원하는 출력 크기의 랜덤 노이즈를 받아 모델을 여러번 통과시켜 이미지의 노이즈를 제거합니다. 각 timestep에서 모델은 *noise residual*을 예측하고 스케줄러는 이를 사용하여 노이즈가 적은 이미지를 예측합니다. 파이프라인은 지정된 추론 스텝수에 도달할 때까지 이 과정을 반복합니다.
|
||||
|
||||
모델과 스케줄러를 별도로 사용하여 파이프라인을 다시 생성하기 위해 자체적인 노이즈 제거 프로세스를 작성해 보겠습니다.
|
||||
|
||||
1. 모델과 스케줄러를 불러옵니다:
|
||||
|
||||
```py
|
||||
>>> from MuseVdiffusers import DDPMScheduler, UNet2DModel
|
||||
|
||||
>>> scheduler = DDPMScheduler.from_pretrained("google/ddpm-cat-256")
|
||||
>>> model = UNet2DModel.from_pretrained("google/ddpm-cat-256").to("cuda")
|
||||
```
|
||||
|
||||
2. 노이즈 제거 프로세스를 실행할 timestep 수를 설정합니다:
|
||||
|
||||
```py
|
||||
>>> scheduler.set_timesteps(50)
|
||||
```
|
||||
|
||||
3. 스케줄러의 timestep을 설정하면 균등한 간격의 구성 요소를 가진 텐서가 생성됩니다.(이 예시에서는 50개) 각 요소는 모델이 이미지의 노이즈를 제거하는 시간 간격에 해당합니다. 나중에 노이즈 제거 루프를 만들 때 이 텐서를 반복하여 이미지의 노이즈를 제거합니다:
|
||||
|
||||
```py
|
||||
>>> scheduler.timesteps
|
||||
tensor([980, 960, 940, 920, 900, 880, 860, 840, 820, 800, 780, 760, 740, 720,
|
||||
700, 680, 660, 640, 620, 600, 580, 560, 540, 520, 500, 480, 460, 440,
|
||||
420, 400, 380, 360, 340, 320, 300, 280, 260, 240, 220, 200, 180, 160,
|
||||
140, 120, 100, 80, 60, 40, 20, 0])
|
||||
```
|
||||
|
||||
4. 원하는 출력과 같은 모양을 가진 랜덤 노이즈를 생성합니다:
|
||||
|
||||
```py
|
||||
>>> import torch
|
||||
|
||||
>>> sample_size = model.config.sample_size
|
||||
>>> noise = torch.randn((1, 3, sample_size, sample_size), device="cuda")
|
||||
```
|
||||
|
||||
5. 이제 timestep을 반복하는 루프를 작성합니다. 각 timestep에서 모델은 [`UNet2DModel.forward`]를 통해 noisy residual을 반환합니다. 스케줄러의 [`~DDPMScheduler.step`] 메서드는 noisy residual, timestep, 그리고 입력을 받아 이전 timestep에서 이미지를 예측합니다. 이 출력은 노이즈 제거 루프의 모델에 대한 다음 입력이 되며, `timesteps` 배열의 끝에 도달할 때까지 반복됩니다.
|
||||
|
||||
```py
|
||||
>>> input = noise
|
||||
|
||||
>>> for t in scheduler.timesteps:
|
||||
... with torch.no_grad():
|
||||
... noisy_residual = model(input, t).sample
|
||||
... previous_noisy_sample = scheduler.step(noisy_residual, t, input).prev_sample
|
||||
... input = previous_noisy_sample
|
||||
```
|
||||
|
||||
이것이 전체 노이즈 제거 프로세스이며, 동일한 패턴을 사용해 모든 diffusion 시스템을 작성할 수 있습니다.
|
||||
|
||||
6. 마지막 단계는 노이즈가 제거된 출력을 이미지로 변환하는 것입니다:
|
||||
|
||||
```py
|
||||
>>> from PIL import Image
|
||||
>>> import numpy as np
|
||||
|
||||
>>> image = (input / 2 + 0.5).clamp(0, 1)
|
||||
>>> image = image.cpu().permute(0, 2, 3, 1).numpy()[0]
|
||||
>>> image = Image.fromarray((image * 255).round().astype("uint8"))
|
||||
>>> image
|
||||
```
|
||||
|
||||
다음 섹션에서는 여러분의 기술을 시험해보고 좀 더 복잡한 Stable Diffusion 파이프라인을 분석해 보겠습니다. 방법은 거의 동일합니다. 필요한 구성요소들을 초기화하고 timestep수를 설정하여 `timestep` 배열을 생성합니다. 노이즈 제거 루프에서 `timestep` 배열이 사용되며, 이 배열의 각 요소에 대해 모델은 노이즈가 적은 이미지를 예측합니다. 노이즈 제거 루프는 `timestep`을 반복하고 각 timestep에서 noise residual을 출력하고 스케줄러는 이를 사용하여 이전 timestep에서 노이즈가 덜한 이미지를 예측합니다. 이 프로세스는 `timestep` 배열의 끝에 도달할 때까지 반복됩니다.
|
||||
|
||||
한번 사용해 봅시다!
|
||||
|
||||
## Stable Diffusion 파이프라인 해체하기
|
||||
|
||||
Stable Diffusion 은 text-to-image *latent diffusion* 모델입니다. latent diffusion 모델이라고 불리는 이유는 실제 픽셀 공간 대신 이미지의 저차원의 표현으로 작업하기 때문이고, 메모리 효율이 더 높습니다. 인코더는 이미지를 더 작은 표현으로 압축하고, 디코더는 압축된 표현을 다시 이미지로 변환합니다. text-to-image 모델의 경우 텍스트 임베딩을 생성하기 위해 tokenizer와 인코더가 필요합니다. 이전 예제에서 이미 UNet 모델과 스케줄러가 필요하다는 것은 알고 계셨을 것입니다.
|
||||
|
||||
보시다시피, 이것은 UNet 모델만 포함된 DDPM 파이프라인보다 더 복잡합니다. Stable Diffusion 모델에는 세 개의 개별 사전학습된 모델이 있습니다.
|
||||
|
||||
<Tip>
|
||||
|
||||
💡 VAE, UNet 및 텍스트 인코더 모델의 작동방식에 대한 자세한 내용은 [How does Stable Diffusion work?](https://huggingface.co/blog/stable_diffusion#how-does-stable-diffusion-work) 블로그를 참조하세요.
|
||||
|
||||
</Tip>
|
||||
|
||||
이제 Stable Diffusion 파이프라인에 필요한 구성요소들이 무엇인지 알았으니, [`~ModelMixin.from_pretrained`] 메서드를 사용해 모든 구성요소를 불러옵니다. 사전학습된 체크포인트 [`runwayml/stable-diffusion-v1-5`](https://huggingface.co/runwayml/stable-diffusion-v1-5)에서 찾을 수 있으며, 각 구성요소들은 별도의 하위 폴더에 저장되어 있습니다:
|
||||
|
||||
```py
|
||||
>>> from PIL import Image
|
||||
>>> import torch
|
||||
>>> from transformers import CLIPTextModel, CLIPTokenizer
|
||||
>>> from MuseVdiffusers import AutoencoderKL, UNet2DConditionModel, PNDMScheduler
|
||||
|
||||
>>> vae = AutoencoderKL.from_pretrained("CompVis/stable-diffusion-v1-4", subfolder="vae")
|
||||
>>> tokenizer = CLIPTokenizer.from_pretrained("CompVis/stable-diffusion-v1-4", subfolder="tokenizer")
|
||||
>>> text_encoder = CLIPTextModel.from_pretrained("CompVis/stable-diffusion-v1-4", subfolder="text_encoder")
|
||||
>>> unet = UNet2DConditionModel.from_pretrained("CompVis/stable-diffusion-v1-4", subfolder="unet")
|
||||
```
|
||||
|
||||
기본 [`PNDMScheduler`] 대신, [`UniPCMultistepScheduler`]로 교체하여 다른 스케줄러를 얼마나 쉽게 연결할 수 있는지 확인합니다:
|
||||
|
||||
```py
|
||||
>>> from MuseVdiffusers import UniPCMultistepScheduler
|
||||
|
||||
>>> scheduler = UniPCMultistepScheduler.from_pretrained("CompVis/stable-diffusion-v1-4", subfolder="scheduler")
|
||||
```
|
||||
|
||||
추론 속도를 높이려면 스케줄러와 달리 학습 가능한 가중치가 있으므로 모델을 GPU로 옮기세요:
|
||||
|
||||
```py
|
||||
>>> torch_device = "cuda"
|
||||
>>> vae.to(torch_device)
|
||||
>>> text_encoder.to(torch_device)
|
||||
>>> unet.to(torch_device)
|
||||
```
|
||||
|
||||
### 텍스트 임베딩 생성하기
|
||||
|
||||
다음 단계는 임베딩을 생성하기 위해 텍스트를 토큰화하는 것입니다. 이 텍스트는 UNet 모델에서 condition으로 사용되고 입력 프롬프트와 유사한 방향으로 diffusion 프로세스를 조정하는 데 사용됩니다.
|
||||
|
||||
<Tip>
|
||||
|
||||
💡 `guidance_scale` 매개변수는 이미지를 생성할 때 프롬프트에 얼마나 많은 가중치를 부여할지 결정합니다.
|
||||
|
||||
</Tip>
|
||||
|
||||
다른 프롬프트를 생성하고 싶다면 원하는 프롬프트를 자유롭게 선택하세요!
|
||||
|
||||
```py
|
||||
>>> prompt = ["a photograph of an astronaut riding a horse"]
|
||||
>>> height = 512 # Stable Diffusion의 기본 높이
|
||||
>>> width = 512 # Stable Diffusion의 기본 너비
|
||||
>>> num_inference_steps = 25 # 노이즈 제거 스텝 수
|
||||
>>> guidance_scale = 7.5 # classifier-free guidance를 위한 scale
|
||||
>>> generator = torch.manual_seed(0) # 초기 잠재 노이즈를 생성하는 seed generator
|
||||
>>> batch_size = len(prompt)
|
||||
```
|
||||
|
||||
텍스트를 토큰화하고 프롬프트에서 임베딩을 생성합니다:
|
||||
|
||||
```py
|
||||
>>> text_input = tokenizer(
|
||||
... prompt, padding="max_length", max_length=tokenizer.model_max_length, truncation=True, return_tensors="pt"
|
||||
... )
|
||||
|
||||
>>> with torch.no_grad():
|
||||
... text_embeddings = text_encoder(text_input.input_ids.to(torch_device))[0]
|
||||
```
|
||||
|
||||
또한 패딩 토큰의 임베딩인 *unconditional 텍스트 임베딩*을 생성해야 합니다. 이 임베딩은 조건부 `text_embeddings`과 동일한 shape(`batch_size` 그리고 `seq_length`)을 가져야 합니다:
|
||||
|
||||
```py
|
||||
>>> max_length = text_input.input_ids.shape[-1]
|
||||
>>> uncond_input = tokenizer([""] * batch_size, padding="max_length", max_length=max_length, return_tensors="pt")
|
||||
>>> uncond_embeddings = text_encoder(uncond_input.input_ids.to(torch_device))[0]
|
||||
```
|
||||
|
||||
두번의 forward pass를 피하기 위해 conditional 임베딩과 unconditional 임베딩을 배치(batch)로 연결하겠습니다:
|
||||
|
||||
```py
|
||||
>>> text_embeddings = torch.cat([uncond_embeddings, text_embeddings])
|
||||
```
|
||||
|
||||
### 랜덤 노이즈 생성
|
||||
|
||||
그다음 diffusion 프로세스의 시작점으로 초기 랜덤 노이즈를 생성합니다. 이것이 이미지의 잠재적 표현이며 점차적으로 노이즈가 제거됩니다. 이 시점에서 `latent` 이미지는 최종 이미지 크기보다 작지만 나중에 모델이 이를 512x512 이미지 크기로 변환하므로 괜찮습니다.
|
||||
|
||||
<Tip>
|
||||
|
||||
💡 `vae` 모델에는 3개의 다운 샘플링 레이어가 있기 때문에 높이와 너비가 8로 나뉩니다. 다음을 실행하여 확인할 수 있습니다:
|
||||
|
||||
```py
|
||||
2 ** (len(vae.config.block_out_channels) - 1) == 8
|
||||
```
|
||||
|
||||
</Tip>
|
||||
|
||||
```py
|
||||
>>> latents = torch.randn(
|
||||
... (batch_size, unet.in_channels, height // 8, width // 8),
|
||||
... generator=generator,
|
||||
... device=torch_device,
|
||||
... )
|
||||
```
|
||||
|
||||
### 이미지 노이즈 제거
|
||||
|
||||
먼저 [`UniPCMultistepScheduler`]와 같은 향상된 스케줄러에 필요한 노이즈 스케일 값인 초기 노이즈 분포 *sigma* 로 입력을 스케일링 하는 것부터 시작합니다:
|
||||
|
||||
```py
|
||||
>>> latents = latents * scheduler.init_noise_sigma
|
||||
```
|
||||
|
||||
마지막 단계는 `latent`의 순수한 노이즈를 점진적으로 프롬프트에 설명된 이미지로 변환하는 노이즈 제거 루프를 생성하는 것입니다. 노이즈 제거 루프는 세 가지 작업을 수행해야 한다는 점을 기억하세요:
|
||||
|
||||
1. 노이즈 제거 중에 사용할 스케줄러의 timesteps를 설정합니다.
|
||||
2. timestep을 따라 반복합니다.
|
||||
3. 각 timestep에서 UNet 모델을 호출하여 noise residual을 예측하고 스케줄러에 전달하여 이전 노이즈 샘플을 계산합니다.
|
||||
|
||||
```py
|
||||
>>> from tqdm.auto import tqdm
|
||||
|
||||
>>> scheduler.set_timesteps(num_inference_steps)
|
||||
|
||||
>>> for t in tqdm(scheduler.timesteps):
|
||||
... # classifier-free guidance를 수행하는 경우 두번의 forward pass를 수행하지 않도록 latent를 확장.
|
||||
... latent_model_input = torch.cat([latents] * 2)
|
||||
|
||||
... latent_model_input = scheduler.scale_model_input(latent_model_input, timestep=t)
|
||||
|
||||
... # noise residual 예측
|
||||
... with torch.no_grad():
|
||||
... noise_pred = unet(latent_model_input, t, encoder_hidden_states=text_embeddings).sample
|
||||
|
||||
... # guidance 수행
|
||||
... noise_pred_uncond, noise_pred_text = noise_pred.chunk(2)
|
||||
... noise_pred = noise_pred_uncond + guidance_scale * (noise_pred_text - noise_pred_uncond)
|
||||
|
||||
... # 이전 노이즈 샘플을 계산 x_t -> x_t-1
|
||||
... latents = scheduler.step(noise_pred, t, latents).prev_sample
|
||||
```
|
||||
|
||||
### 이미지 디코딩
|
||||
|
||||
마지막 단계는 `vae`를 이용하여 잠재 표현을 이미지로 디코딩하고 `sample`과 함께 디코딩된 출력을 얻는 것입니다:
|
||||
|
||||
```py
|
||||
# latent를 스케일링하고 vae로 이미지 디코딩
|
||||
latents = 1 / 0.18215 * latents
|
||||
with torch.no_grad():
|
||||
image = vae.decode(latents).sample
|
||||
```
|
||||
|
||||
마지막으로 이미지를 `PIL.Image`로 변환하면 생성된 이미지를 확인할 수 있습니다!
|
||||
|
||||
```py
|
||||
>>> image = (image / 2 + 0.5).clamp(0, 1)
|
||||
>>> image = image.detach().cpu().permute(0, 2, 3, 1).numpy()
|
||||
>>> images = (image * 255).round().astype("uint8")
|
||||
>>> pil_images = [Image.fromarray(image) for image in images]
|
||||
>>> pil_images[0]
|
||||
```
|
||||
|
||||
<div class="flex justify-center">
|
||||
<img src="https://huggingface.co/blog/assets/98_stable_diffusion/stable_diffusion_k_lms.png"/>
|
||||
</div>
|
||||
|
||||
## 다음 단계
|
||||
|
||||
기본 파이프라인부터 복잡한 파이프라인까지, 자신만의 diffusion 시스템을 작성하는 데 필요한 것은 노이즈 제거 루프뿐이라는 것을 알 수 있었습니다. 이 루프는 스케줄러의 timesteps를 설정하고, 이를 반복하며, UNet 모델을 호출하여 noise residual을 예측하고 스케줄러에 전달하여 이전 노이즈 샘플을 계산하는 과정을 번갈아 가며 수행해야 합니다.
|
||||
|
||||
이것이 바로 🧨 Diffusers가 설계된 목적입니다: 모델과 스케줄러를 사용해 자신만의 diffusion 시스템을 직관적이고 쉽게 작성할 수 있도록 하기 위해서입니다.
|
||||
|
||||
다음 단계를 자유롭게 진행하세요:
|
||||
|
||||
* 🧨 Diffusers에 [파이프라인 구축 및 기여](using-diffusers/#contribute_pipeline)하는 방법을 알아보세요. 여러분이 어떤 아이디어를 내놓을지 기대됩니다!
|
||||
* 라이브러리에서 [기본 파이프라인](./api/pipelines/overview)을 살펴보고, 모델과 스케줄러를 별도로 사용하여 파이프라인을 처음부터 해체하고 빌드할 수 있는지 확인해 보세요.
|
||||
Reference in New Issue
Block a user