init commit
This commit is contained in:
 AIFSH
@@ -0,0 +1 @@
|
||||
__pycache__
|
||||
+147
@@ -0,0 +1,147 @@
|
||||
import os,sys
|
||||
now_dir = os.path.dirname(os.path.abspath(__file__))
|
||||
sys.path.append(now_dir)
|
||||
|
||||
import math
|
||||
import folder_paths
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
from huggingface_hub import snapshot_download
|
||||
from viewcrafter.viewcrafter import ViewCrafter
|
||||
from viewcrafter.configs.infer_config import get_parser
|
||||
|
||||
output_dir = folder_paths.get_output_directory()
|
||||
ckpt_dir = os.path.join(now_dir,"checkpoints")
|
||||
default_traj_txt = "0 -40\n0 0\n0. -0.2"
|
||||
|
||||
|
||||
|
||||
class ViewCrafterTxTNode:
|
||||
def __init__(self):
|
||||
self.pvd = None
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required":{
|
||||
"img":("IMAGE",),
|
||||
"traj_txt":(["left","loop1","loop2","wave1","zoomin1"],),
|
||||
"video_length":([25,16],),
|
||||
"ddim_steps":("INT",{
|
||||
"default":50,
|
||||
}),
|
||||
"center_scale":("FLOAT",{
|
||||
"default":1.,
|
||||
"min":0.0,
|
||||
"max":2.0,
|
||||
"display":"slider",
|
||||
}),
|
||||
"elevation":("FLOAT",{
|
||||
"default":5.,
|
||||
}),
|
||||
"d_theta":("INT",{
|
||||
"default":-30,
|
||||
"min":-40,
|
||||
"max":40,
|
||||
"display":"slider",
|
||||
}),
|
||||
"d_phi":("INT",{
|
||||
"default":45,
|
||||
"min":-45,
|
||||
"max":45,
|
||||
"step":5,
|
||||
"display":"slider",
|
||||
}),
|
||||
"d_r":("FLOAT",{
|
||||
"default":-0.5,
|
||||
"min":-0.5,
|
||||
"max":0.5,
|
||||
"display":"slider",
|
||||
}),
|
||||
"seed":("INT",{
|
||||
"default":42,
|
||||
}),
|
||||
},
|
||||
"optional":{
|
||||
"custom_traj_txt":("STRING",{
|
||||
"multiline": True,
|
||||
"default":default_traj_txt
|
||||
}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("VIDEO","VIDEO",)
|
||||
RETURN_NAMES = ("result_video","traj_video",)
|
||||
|
||||
FUNCTION = "gen_video"
|
||||
|
||||
#OUTPUT_NODE = False
|
||||
|
||||
CATEGORY = "AIFSH_ViewCrafter"
|
||||
|
||||
def gen_video(self,img,traj_txt,video_length,ddim_steps,center_scale,elevation,
|
||||
d_theta,d_phi,d_r,seed,custom_traj_txt=default_traj_txt):
|
||||
parser = get_parser()
|
||||
opts = parser.parse_args()
|
||||
opts.exp_name = "AIFSH"
|
||||
opts.save_dir = os.path.join(output_dir,"viewcrafter")
|
||||
os.makedirs(opts.save_dir,exist_ok=True)
|
||||
|
||||
img = img.numpy()[0] * 255
|
||||
img_np = img.astype(np.uint8)
|
||||
print(img_np.shape)
|
||||
img_pil = Image.fromarray(img_np)
|
||||
org_h, org_w = img_pil.size
|
||||
height,width = (1024,math.ceil(1024 * org_w/org_h/64)*64) if org_h > org_w else (math.ceil(1024 * org_h/org_w/64)*64,1024)
|
||||
img_pil = img_pil.resize((height,width))
|
||||
print(f"from {(org_h,org_w)} to {(height, width)}")
|
||||
opts.height = height
|
||||
opts.width = width
|
||||
tmp_img_path = os.path.join(opts.save_dir,"tmp.png")
|
||||
img_pil.save(tmp_img_path)
|
||||
|
||||
opts.image_dir = tmp_img_path
|
||||
if custom_traj_txt != default_traj_txt:
|
||||
traj_path = os.path.join(opts.save_dir,"tmp.txt")
|
||||
with open(traj_path,'w',encoding="utf-8") as w:
|
||||
w.write(custom_traj_txt)
|
||||
else:
|
||||
traj_path = os.path.join(now_dir,"viewcrafter","trajs",f"{traj_txt}.txt")
|
||||
opts.traj_txt = traj_path
|
||||
opts.mode = "single_view_txt"
|
||||
opts.center_scale = center_scale
|
||||
opts.elevation = elevation
|
||||
opts.seed = seed
|
||||
opts.d_theta = d_theta
|
||||
opts.d_phi = d_phi
|
||||
opts.d_r = d_r
|
||||
ckpt_name = f"ViewCrafter_{video_length}"
|
||||
ckpt_path = os.path.join(ckpt_dir,ckpt_name,"model.ckpt")
|
||||
if not os.path.exists(ckpt_path):
|
||||
snapshot_download(repo_id=f"Drexubery/{ckpt_name}",local_dir=os.path.join(ckpt_dir,ckpt_name))
|
||||
opts.ckpt_path = ckpt_path
|
||||
opts.config = os.path.join(now_dir,"viewcrafter","configs","inference_pvd_1024.yaml")
|
||||
opts.ddim_steps = ddim_steps
|
||||
opts.video_length = video_length
|
||||
opts.device = "cuda"
|
||||
opts.model_path = os.path.join(ckpt_dir,"DUSt3R_ViTLarge_BaseDecoder_512_dpt.pth")
|
||||
if not os.path.exists(opts.model_path):
|
||||
os.system(f"wget https://download.europe.naverlabs.com/ComputerVision/DUSt3R/DUSt3R_ViTLarge_BaseDecoder_512_dpt.pth -P {ckpt_dir}")
|
||||
|
||||
print(opts)
|
||||
if self.pvd is None:
|
||||
self.pvd = ViewCrafter(opts)
|
||||
self.pvd.nvs_single_view()
|
||||
|
||||
res_video = os.path.join(opts.save_dir, 'diffusion0.mp4')
|
||||
traj_video = os.path.join(opts.save_dir,'viz_traj.mp4')
|
||||
return (res_video, traj_video,)
|
||||
|
||||
|
||||
WEB_DIRECTORY = "./js"
|
||||
from .util_nodes import PreViewVideo,LoadVideo
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"LoadVideo":LoadVideo,
|
||||
"PreViewVideo":PreViewVideo,
|
||||
"ViewCrafterTxTNode": ViewCrafterTxTNode
|
||||
}
|
||||
@@ -0,0 +1,154 @@
|
||||
import { app } from "../../../scripts/app.js";
|
||||
import { api } from '../../../scripts/api.js'
|
||||
|
||||
function fitHeight(node) {
|
||||
node.setSize([node.size[0], node.computeSize([node.size[0], node.size[1]])[1]])
|
||||
node?.graph?.setDirtyCanvas(true);
|
||||
}
|
||||
function chainCallback(object, property, callback) {
|
||||
if (object == undefined) {
|
||||
//This should not happen.
|
||||
console.error("Tried to add callback to non-existant object")
|
||||
return;
|
||||
}
|
||||
if (property in object) {
|
||||
const callback_orig = object[property]
|
||||
object[property] = function () {
|
||||
const r = callback_orig.apply(this, arguments);
|
||||
callback.apply(this, arguments);
|
||||
return r
|
||||
};
|
||||
} else {
|
||||
object[property] = callback;
|
||||
}
|
||||
}
|
||||
|
||||
function addPreviewOptions(nodeType) {
|
||||
chainCallback(nodeType.prototype, "getExtraMenuOptions", function(_, options) {
|
||||
// The intended way of appending options is returning a list of extra options,
|
||||
// but this isn't used in widgetInputs.js and would require
|
||||
// less generalization of chainCallback
|
||||
let optNew = []
|
||||
try {
|
||||
const previewWidget = this.widgets.find((w) => w.name === "videopreview");
|
||||
|
||||
let url = null
|
||||
if (previewWidget.videoEl?.hidden == false && previewWidget.videoEl.src) {
|
||||
//Use full quality video
|
||||
//url = api.apiURL('/view?' + new URLSearchParams(previewWidget.value.params));
|
||||
url = previewWidget.videoEl.src
|
||||
}
|
||||
if (url) {
|
||||
optNew.push(
|
||||
{
|
||||
content: "Open preview",
|
||||
callback: () => {
|
||||
window.open(url, "_blank")
|
||||
},
|
||||
},
|
||||
{
|
||||
content: "Save preview",
|
||||
callback: () => {
|
||||
const a = document.createElement("a");
|
||||
a.href = url;
|
||||
a.setAttribute("download", new URLSearchParams(previewWidget.value.params).get("filename"));
|
||||
document.body.append(a);
|
||||
a.click();
|
||||
requestAnimationFrame(() => a.remove());
|
||||
},
|
||||
}
|
||||
);
|
||||
}
|
||||
if(options.length > 0 && options[0] != null && optNew.length > 0) {
|
||||
optNew.push(null);
|
||||
}
|
||||
options.unshift(...optNew);
|
||||
|
||||
} catch (error) {
|
||||
console.log(error);
|
||||
}
|
||||
|
||||
});
|
||||
}
|
||||
function previewVideo(node,file,type){
|
||||
var element = document.createElement("div");
|
||||
const previewNode = node;
|
||||
var previewWidget = node.addDOMWidget("videopreview", "preview", element, {
|
||||
serialize: false,
|
||||
hideOnZoom: false,
|
||||
getValue() {
|
||||
return element.value;
|
||||
},
|
||||
setValue(v) {
|
||||
element.value = v;
|
||||
},
|
||||
});
|
||||
previewWidget.computeSize = function(width) {
|
||||
if (this.aspectRatio && !this.parentEl.hidden) {
|
||||
let height = (previewNode.size[0]-20)/ this.aspectRatio + 10;
|
||||
if (!(height > 0)) {
|
||||
height = 0;
|
||||
}
|
||||
this.computedHeight = height + 10;
|
||||
return [width, height];
|
||||
}
|
||||
return [width, -4];//no loaded src, widget should not display
|
||||
}
|
||||
// element.style['pointer-events'] = "none"
|
||||
previewWidget.value = {hidden: false, paused: false, params: {}}
|
||||
previewWidget.parentEl = document.createElement("div");
|
||||
previewWidget.parentEl.className = "video_preview";
|
||||
previewWidget.parentEl.style['width'] = "100%"
|
||||
element.appendChild(previewWidget.parentEl);
|
||||
previewWidget.videoEl = document.createElement("video");
|
||||
previewWidget.videoEl.controls = true;
|
||||
previewWidget.videoEl.loop = false;
|
||||
previewWidget.videoEl.muted = false;
|
||||
previewWidget.videoEl.style['width'] = "100%"
|
||||
previewWidget.videoEl.addEventListener("loadedmetadata", () => {
|
||||
|
||||
previewWidget.aspectRatio = previewWidget.videoEl.videoWidth / previewWidget.videoEl.videoHeight;
|
||||
fitHeight(this);
|
||||
});
|
||||
previewWidget.videoEl.addEventListener("error", () => {
|
||||
//TODO: consider a way to properly notify the user why a preview isn't shown.
|
||||
previewWidget.parentEl.hidden = true;
|
||||
fitHeight(this);
|
||||
});
|
||||
|
||||
let params = {
|
||||
"filename": file,
|
||||
"type": type,
|
||||
}
|
||||
|
||||
previewWidget.parentEl.hidden = previewWidget.value.hidden;
|
||||
previewWidget.videoEl.autoplay = !previewWidget.value.paused && !previewWidget.value.hidden;
|
||||
let target_width = 256
|
||||
if (element.style?.width) {
|
||||
//overscale to allow scrolling. Endpoint won't return higher than native
|
||||
target_width = element.style.width.slice(0,-2)*2;
|
||||
}
|
||||
if (!params.force_size || params.force_size.includes("?") || params.force_size == "Disabled") {
|
||||
params.force_size = target_width+"x?"
|
||||
} else {
|
||||
let size = params.force_size.split("x")
|
||||
let ar = parseInt(size[0])/parseInt(size[1])
|
||||
params.force_size = target_width+"x"+(target_width/ar)
|
||||
}
|
||||
|
||||
previewWidget.videoEl.src = api.apiURL('/view?' + new URLSearchParams(params));
|
||||
|
||||
previewWidget.videoEl.hidden = false;
|
||||
previewWidget.parentEl.appendChild(previewWidget.videoEl)
|
||||
}
|
||||
|
||||
app.registerExtension({
|
||||
name: "ViewCrafter.VideoPreviewer",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData, app) {
|
||||
if (nodeData?.name == "PreViewVideo") {
|
||||
nodeType.prototype.onExecuted = function (data) {
|
||||
previewVideo(this, data.video[0], data.video[1]);
|
||||
}
|
||||
}
|
||||
}
|
||||
});
|
||||
@@ -0,0 +1,203 @@
|
||||
import { app } from "../../../scripts/app.js";
|
||||
import { api } from '../../../scripts/api.js'
|
||||
import { ComfyWidgets } from "../../../scripts/widgets.js"
|
||||
|
||||
function fitHeight(node) {
|
||||
node.setSize([node.size[0], node.computeSize([node.size[0], node.size[1]])[1]])
|
||||
node?.graph?.setDirtyCanvas(true);
|
||||
}
|
||||
|
||||
function previewVideo(node,file){
|
||||
while (node.widgets.length > 2){
|
||||
node.widgets.pop()
|
||||
}
|
||||
try {
|
||||
var el = document.getElementById("uploadVideo");
|
||||
el.remove();
|
||||
} catch (error) {
|
||||
console.log(error);
|
||||
}
|
||||
var element = document.createElement("div");
|
||||
element.id = "uploadVideo";
|
||||
const previewNode = node;
|
||||
var previewWidget = node.addDOMWidget("videopreview", "preview", element, {
|
||||
serialize: false,
|
||||
hideOnZoom: false,
|
||||
getValue() {
|
||||
return element.value;
|
||||
},
|
||||
setValue(v) {
|
||||
element.value = v;
|
||||
},
|
||||
});
|
||||
previewWidget.computeSize = function(width) {
|
||||
if (this.aspectRatio && !this.parentEl.hidden) {
|
||||
let height = (previewNode.size[0]-20)/ this.aspectRatio + 10;
|
||||
if (!(height > 0)) {
|
||||
height = 0;
|
||||
}
|
||||
this.computedHeight = height + 10;
|
||||
return [width, height];
|
||||
}
|
||||
return [width, -4];//no loaded src, widget should not display
|
||||
}
|
||||
// element.style['pointer-events'] = "none"
|
||||
previewWidget.value = {hidden: false, paused: false, params: {}}
|
||||
previewWidget.parentEl = document.createElement("div");
|
||||
previewWidget.parentEl.className = "video_preview";
|
||||
previewWidget.parentEl.style['width'] = "100%"
|
||||
element.appendChild(previewWidget.parentEl);
|
||||
previewWidget.videoEl = document.createElement("video");
|
||||
previewWidget.videoEl.controls = true;
|
||||
previewWidget.videoEl.loop = false;
|
||||
previewWidget.videoEl.muted = false;
|
||||
previewWidget.videoEl.style['width'] = "100%"
|
||||
previewWidget.videoEl.addEventListener("loadedmetadata", () => {
|
||||
|
||||
previewWidget.aspectRatio = previewWidget.videoEl.videoWidth / previewWidget.videoEl.videoHeight;
|
||||
fitHeight(this);
|
||||
});
|
||||
previewWidget.videoEl.addEventListener("error", () => {
|
||||
//TODO: consider a way to properly notify the user why a preview isn't shown.
|
||||
previewWidget.parentEl.hidden = true;
|
||||
fitHeight(this);
|
||||
});
|
||||
|
||||
let params = {
|
||||
"filename": file,
|
||||
"type": "input",
|
||||
}
|
||||
|
||||
previewWidget.parentEl.hidden = previewWidget.value.hidden;
|
||||
previewWidget.videoEl.autoplay = !previewWidget.value.paused && !previewWidget.value.hidden;
|
||||
let target_width = 256
|
||||
if (element.style?.width) {
|
||||
//overscale to allow scrolling. Endpoint won't return higher than native
|
||||
target_width = element.style.width.slice(0,-2)*2;
|
||||
}
|
||||
if (!params.force_size || params.force_size.includes("?") || params.force_size == "Disabled") {
|
||||
params.force_size = target_width+"x?"
|
||||
} else {
|
||||
let size = params.force_size.split("x")
|
||||
let ar = parseInt(size[0])/parseInt(size[1])
|
||||
params.force_size = target_width+"x"+(target_width/ar)
|
||||
}
|
||||
|
||||
previewWidget.videoEl.src = api.apiURL('/view?' + new URLSearchParams(params));
|
||||
|
||||
previewWidget.videoEl.hidden = false;
|
||||
previewWidget.parentEl.appendChild(previewWidget.videoEl)
|
||||
}
|
||||
|
||||
function videoUpload(node, inputName, inputData, app) {
|
||||
const videoWidget = node.widgets.find((w) => w.name === "video");
|
||||
let uploadWidget;
|
||||
/*
|
||||
A method that returns the required style for the html
|
||||
*/
|
||||
var default_value = videoWidget.value;
|
||||
Object.defineProperty(videoWidget, "value", {
|
||||
set : function(value) {
|
||||
this._real_value = value;
|
||||
},
|
||||
|
||||
get : function() {
|
||||
let value = "";
|
||||
if (this._real_value) {
|
||||
value = this._real_value;
|
||||
} else {
|
||||
return default_value;
|
||||
}
|
||||
|
||||
if (value.filename) {
|
||||
let real_value = value;
|
||||
value = "";
|
||||
if (real_value.subfolder) {
|
||||
value = real_value.subfolder + "/";
|
||||
}
|
||||
|
||||
value += real_value.filename;
|
||||
|
||||
if(real_value.type && real_value.type !== "input")
|
||||
value += ` [${real_value.type}]`;
|
||||
}
|
||||
return value;
|
||||
}
|
||||
});
|
||||
async function uploadFile(file, updateNode, pasted = false) {
|
||||
try {
|
||||
// Wrap file in formdata so it includes filename
|
||||
const body = new FormData();
|
||||
body.append("image", file);
|
||||
if (pasted) body.append("subfolder", "pasted");
|
||||
const resp = await api.fetchApi("/upload/image", {
|
||||
method: "POST",
|
||||
body,
|
||||
});
|
||||
|
||||
if (resp.status === 200) {
|
||||
const data = await resp.json();
|
||||
// Add the file to the dropdown list and update the widget value
|
||||
let path = data.name;
|
||||
if (data.subfolder) path = data.subfolder + "/" + path;
|
||||
|
||||
if (!videoWidget.options.values.includes(path)) {
|
||||
videoWidget.options.values.push(path);
|
||||
}
|
||||
|
||||
if (updateNode) {
|
||||
videoWidget.value = path;
|
||||
previewVideo(node,path)
|
||||
|
||||
}
|
||||
} else {
|
||||
alert(resp.status + " - " + resp.statusText);
|
||||
}
|
||||
} catch (error) {
|
||||
alert(error);
|
||||
}
|
||||
}
|
||||
|
||||
const fileInput = document.createElement("input");
|
||||
Object.assign(fileInput, {
|
||||
type: "file",
|
||||
accept: "video/webm,video/mp4,video/mkv,video/avi",
|
||||
style: "display: none",
|
||||
onchange: async () => {
|
||||
if (fileInput.files.length) {
|
||||
await uploadFile(fileInput.files[0], true);
|
||||
}
|
||||
},
|
||||
});
|
||||
document.body.append(fileInput);
|
||||
|
||||
// Create the button widget for selecting the files
|
||||
uploadWidget = node.addWidget("button", "choose video file to upload", "Video", () => {
|
||||
fileInput.click();
|
||||
});
|
||||
|
||||
uploadWidget.serialize = false;
|
||||
|
||||
previewVideo(node, videoWidget.value);
|
||||
const cb = node.callback;
|
||||
videoWidget.callback = function () {
|
||||
previewVideo(node,videoWidget.value);
|
||||
if (cb) {
|
||||
return cb.apply(this, arguments);
|
||||
}
|
||||
};
|
||||
|
||||
return { widget: uploadWidget };
|
||||
}
|
||||
|
||||
ComfyWidgets.VIDEOPLOAD = videoUpload;
|
||||
|
||||
app.registerExtension({
|
||||
name: "ViewCrafter.UploadVideo",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData, app) {
|
||||
if (nodeData?.name == "LoadVideo") {
|
||||
nodeData.input.required.upload = ["VIDEOPLOAD"];
|
||||
}
|
||||
},
|
||||
});
|
||||
|
||||
@@ -0,0 +1,40 @@
|
||||
av==10.0.0
|
||||
decord==0.6.0
|
||||
einops==0.6.1
|
||||
imageio==2.27.0
|
||||
imageio-ffmpeg==0.4.8
|
||||
torch==1.13.1
|
||||
torchvision
|
||||
kornia
|
||||
matplotlib==3.9.2
|
||||
moviepy==1.0.3
|
||||
numpy==1.23.5
|
||||
open-clip-torch==2.17.1
|
||||
opencv-python==4.7.0.72
|
||||
Pillow==9.4.0
|
||||
pip==23.0.1
|
||||
pyglet==1.5.0
|
||||
pytorch-lightning==1.9.3
|
||||
PyYAML==6.0
|
||||
roma==1.5.0
|
||||
scikit-image==0.20.0
|
||||
scikit-learn==1.2.2
|
||||
scipy==1.9.1
|
||||
tensorboard==2.12.2
|
||||
timm==0.6.13
|
||||
tqdm==4.65.0
|
||||
transformers==4.28.1
|
||||
trimesh==4.4.3
|
||||
xformers
|
||||
gradio==3.37.0
|
||||
gradio_client==0.7.1
|
||||
omegaconf==2.3.0
|
||||
triton
|
||||
altair==5.4.0
|
||||
certifi==2024.7.4
|
||||
grpcio==1.66.0
|
||||
httpx==0.27.0
|
||||
Pygments==2.18.0
|
||||
starlette==0.38.2
|
||||
tifffile==2024.8.24
|
||||
yarl==1.9.4
|
||||
@@ -0,0 +1,47 @@
|
||||
import os
|
||||
import folder_paths
|
||||
now_dir = os.path.dirname(os.path.abspath(__file__))
|
||||
input_dir = folder_paths.get_input_directory()
|
||||
output_dir = folder_paths.get_output_directory()
|
||||
|
||||
class LoadVideo:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
files = [f for f in os.listdir(input_dir) if os.path.isfile(os.path.join(input_dir, f)) and f.split('.')[-1] in ["mp4", "webm","mkv","avi"]]
|
||||
return {"required":{
|
||||
"video":(files,),
|
||||
}}
|
||||
|
||||
CATEGORY = "AIFSH_ViewCrafter"
|
||||
DESCRIPTION = "hello world!"
|
||||
|
||||
RETURN_TYPES = ("VIDEO",)
|
||||
|
||||
OUTPUT_NODE = False
|
||||
|
||||
FUNCTION = "load_video"
|
||||
|
||||
def load_video(self, video):
|
||||
video_path = os.path.join(input_dir,video)
|
||||
return (video_path,)
|
||||
|
||||
class PreViewVideo:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {"required":{
|
||||
"video":("VIDEO",),
|
||||
}}
|
||||
|
||||
CATEGORY = "AIFSH_ViewCrafter"
|
||||
DESCRIPTION = "hello world!"
|
||||
|
||||
RETURN_TYPES = ()
|
||||
|
||||
OUTPUT_NODE = True
|
||||
|
||||
FUNCTION = "load_video"
|
||||
|
||||
def load_video(self, video):
|
||||
video_name = os.path.basename(video)
|
||||
video_path_name = os.path.basename(os.path.dirname(video))
|
||||
return {"ui":{"video":[video_name,video_path_name]}}
|
||||
@@ -0,0 +1,58 @@
|
||||
import os
|
||||
import argparse
|
||||
|
||||
def get_parser():
|
||||
parser = argparse.ArgumentParser()
|
||||
|
||||
## general
|
||||
parser.add_argument('--image_dir', type=str, default='./test/images/fruit.png', help='Image file path')
|
||||
parser.add_argument('--out_dir', type=str, default='./output', help='Output directory')
|
||||
parser.add_argument('--device', type=str, default='cuda:0', help='The device to use')
|
||||
parser.add_argument('--exp_name', type=str, default=None, help='Experiment name, use image file name by default')
|
||||
|
||||
## renderer
|
||||
parser.add_argument('--mode', type=str, default='single_view_txt', help="Currently we support 'single_view_txt' and 'single_view_target'")
|
||||
parser.add_argument('--traj_txt', type=str, help="Required for 'single_view_txt' mode, a txt file that specify camera trajectory")
|
||||
parser.add_argument('--elevation', type=float, default=5., help='The elevation angle of the input image in degree. Estimate a rough value based on your visual judgment' )
|
||||
parser.add_argument('--center_scale', type=float, default=1., help='Range: (0, 2]. Scale factor for the spherical radius (r). By default, r is set to the depth value of the center pixel (H//2, W//2) of the reference image')
|
||||
parser.add_argument('--d_theta', nargs='+', type=int, default=10., help="Range: [-40, 40]. Required for 'single_view_target' mode, specify target theta angle as theta + d_theta")
|
||||
parser.add_argument('--d_phi', nargs='+', type=int, default=30., help="Range: [-45, 45]. Required for 'single_view_target' mode, specify target phi angle as phi + d_phi")
|
||||
parser.add_argument('--d_r', nargs='+', type=float, default=-.2, help="Range: [-.5, .5]. Required for 'single_view_target' mode, specify target radius as r + r*dr")
|
||||
parser.add_argument('--mask_image', type=bool, default=False, help='Required for mulitpule reference images and iterative mode')
|
||||
parser.add_argument('--mask_pc', type=bool, default=True, help='Required for mulitpule reference images and iterative mode')
|
||||
parser.add_argument('--reduce_pc', default=False, help='Required for mulitpule reference images and iterative mode')
|
||||
parser.add_argument('--bg_trd', type=float, default=0., help='Required for mulitpule reference images and iterative mode, set to 0. is no mask')
|
||||
parser.add_argument('--dpt_trd', type=float, default=1., help='Required for mulitpule reference images and iterative mode, limit the max depth by * dpt_trd')
|
||||
|
||||
|
||||
## diffusion
|
||||
parser.add_argument("--ckpt_path", type=str, default='./checkpoints/model.ckpt', help="checkpoint path")
|
||||
parser.add_argument("--config", type=str, default='./configs/inference_pvd_1024.yaml', help="config (yaml) path")
|
||||
parser.add_argument("--ddim_steps", type=int, default=50, help="steps of ddim if positive, otherwise use DDPM, reduce to 10 to speed up inference")
|
||||
parser.add_argument("--ddim_eta", type=float, default=1.0, help="eta for ddim sampling (0.0 yields deterministic sampling)")
|
||||
parser.add_argument("--bs", type=int, default=1, help="batch size for inference, should be one")
|
||||
parser.add_argument("--height", type=int, default=576, help="image height, in pixel space")
|
||||
parser.add_argument("--width", type=int, default=1024, help="image width, in pixel space")
|
||||
parser.add_argument("--frame_stride", type=int, default=10, help="Fixed")
|
||||
parser.add_argument("--unconditional_guidance_scale", type=float, default=7.5, help="prompt classifier-free guidance")
|
||||
parser.add_argument("--seed", type=int, default=123, help="seed for seed_everything")
|
||||
parser.add_argument("--video_length", type=int, default=25, help="inference video length, change to 16 if you use 16 frame model")
|
||||
parser.add_argument("--negative_prompt", default=False, help="unused")
|
||||
parser.add_argument("--text_input", default=True, help="unused")
|
||||
parser.add_argument("--prompt", type=str, default='Rotating view of a scene', help="Fixed")
|
||||
parser.add_argument("--multiple_cond_cfg", action='store_true', default=False, help="use multi-condition cfg or not")
|
||||
parser.add_argument("--cfg_img", type=float, default=None, help="guidance scale for image conditioning")
|
||||
parser.add_argument("--timestep_spacing", type=str, default="uniform_trailing", help="The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information.")
|
||||
parser.add_argument("--guidance_rescale", type=float, default=0.7, help="guidance rescale in [Common Diffusion Noise Schedules and Sample Steps are Flawed](https://huggingface.co/papers/2305.08891)")
|
||||
parser.add_argument("--perframe_ae", default=True, help="if we use per-frame AE decoding, set it to True to save GPU memory, especially for the model of 576x1024")
|
||||
parser.add_argument("--n_samples", type=int, default=1, help="num of samples per prompt")
|
||||
|
||||
## dust3r
|
||||
parser.add_argument('--model_path', type=str, default='./checkpoints/DUSt3R_ViTLarge_BaseDecoder_512_dpt.pth', help='The path of the model')
|
||||
parser.add_argument('--batch_size', default=1)
|
||||
parser.add_argument('--schedule', type=str, default='linear')
|
||||
parser.add_argument('--niter', default=300)
|
||||
parser.add_argument('--lr', default=0.01)
|
||||
parser.add_argument('--min_conf_thr', default=3.0) # minimum=1.0, maximum=20
|
||||
|
||||
return parser
|
||||
@@ -0,0 +1,111 @@
|
||||
model:
|
||||
pretrained_checkpoint: ./
|
||||
base_learning_rate: 1.0e-05
|
||||
scale_lr: False
|
||||
target: lvdm.models.ddpm3d.VIPLatentDiffusion
|
||||
params:
|
||||
rescale_betas_zero_snr: True
|
||||
parameterization: "v"
|
||||
linear_start: 0.00085
|
||||
linear_end: 0.012
|
||||
num_timesteps_cond: 1
|
||||
log_every_t: 200
|
||||
timesteps: 1000
|
||||
first_stage_key: video
|
||||
cond_stage_key: caption
|
||||
cond_stage_trainable: False
|
||||
image_proj_model_trainable: True
|
||||
conditioning_key: hybrid
|
||||
image_size: [72, 128]
|
||||
channels: 4
|
||||
scale_by_std: False
|
||||
scale_factor: 0.18215
|
||||
use_ema: False
|
||||
uncond_prob: 0.05
|
||||
uncond_type: 'empty_seq'
|
||||
rand_cond_frame: true
|
||||
use_dynamic_rescale: true
|
||||
base_scale: 0.3
|
||||
fps_condition_type: 'fps'
|
||||
perframe_ae: True
|
||||
loop_video: Flase
|
||||
|
||||
unet_config:
|
||||
target: lvdm.modules.networks.openaimodel3d.UNetModel
|
||||
params:
|
||||
in_channels: 8
|
||||
out_channels: 4
|
||||
model_channels: 320
|
||||
attention_resolutions:
|
||||
- 4
|
||||
- 2
|
||||
- 1
|
||||
num_res_blocks: 2
|
||||
channel_mult:
|
||||
- 1
|
||||
- 2
|
||||
- 4
|
||||
- 4
|
||||
dropout: 0.1
|
||||
num_head_channels: 64
|
||||
transformer_depth: 1
|
||||
context_dim: 1024
|
||||
use_linear: true
|
||||
use_checkpoint: True
|
||||
temporal_conv: True
|
||||
temporal_attention: True
|
||||
temporal_selfatt_only: true
|
||||
use_relative_position: false
|
||||
use_causal_attention: False
|
||||
temporal_length: 16
|
||||
addition_attention: true
|
||||
image_cross_attention: true
|
||||
default_fs: 10
|
||||
fs_condition: true
|
||||
|
||||
first_stage_config:
|
||||
target: lvdm.models.autoencoder.AutoencoderKL
|
||||
params:
|
||||
embed_dim: 4
|
||||
monitor: val/rec_loss
|
||||
ddconfig:
|
||||
double_z: True
|
||||
z_channels: 4
|
||||
resolution: 256
|
||||
in_channels: 3
|
||||
out_ch: 3
|
||||
ch: 128
|
||||
ch_mult:
|
||||
- 1
|
||||
- 2
|
||||
- 4
|
||||
- 4
|
||||
num_res_blocks: 2
|
||||
attn_resolutions: []
|
||||
dropout: 0.0
|
||||
lossconfig:
|
||||
target: torch.nn.Identity
|
||||
|
||||
cond_stage_config:
|
||||
target: lvdm.modules.encoders.condition.FrozenOpenCLIPEmbedder
|
||||
params:
|
||||
freeze: true
|
||||
layer: "penultimate"
|
||||
|
||||
img_cond_stage_config:
|
||||
target: lvdm.modules.encoders.condition.FrozenOpenCLIPImageEmbedderV2
|
||||
params:
|
||||
freeze: true
|
||||
|
||||
image_proj_stage_config:
|
||||
target: lvdm.modules.encoders.resampler.Resampler
|
||||
params:
|
||||
dim: 1024
|
||||
depth: 4
|
||||
dim_head: 64
|
||||
heads: 12
|
||||
num_queries: 16
|
||||
embedding_dim: 1280
|
||||
output_dim: 1024
|
||||
ff_mult: 4
|
||||
video_length: 16
|
||||
@@ -0,0 +1,112 @@
|
||||
model:
|
||||
pretrained_checkpoint: /apdcephfs_cq10/share_1290939/vg_share/vip3d_share/3d_320_512_SD-IPA_ztsnr_v_builton11_10k_DL3DVdust3r_fps10_allmode/epoch=7-step=60000.ckpt
|
||||
base_learning_rate: 1.0e-05
|
||||
scale_lr: False
|
||||
target: lvdm.models.ddpm3d.VIPLatentDiffusion
|
||||
params:
|
||||
rescale_betas_zero_snr: True
|
||||
parameterization: "v"
|
||||
linear_start: 0.00085
|
||||
linear_end: 0.012
|
||||
num_timesteps_cond: 1
|
||||
log_every_t: 200
|
||||
timesteps: 1000
|
||||
first_stage_key: video
|
||||
cond_stage_key: caption
|
||||
cond_stage_trainable: False
|
||||
image_proj_model_trainable: True
|
||||
conditioning_key: hybrid
|
||||
image_size: [40, 64]
|
||||
channels: 4
|
||||
scale_by_std: False
|
||||
scale_factor: 0.18215
|
||||
use_ema: False
|
||||
uncond_prob: 0.05
|
||||
uncond_type: 'empty_seq'
|
||||
rand_cond_frame: true
|
||||
use_dynamic_rescale: true
|
||||
base_scale: 0.7
|
||||
fps_condition_type: 'fps'
|
||||
perframe_ae: True
|
||||
loop_video: False
|
||||
fix_temporal: True
|
||||
|
||||
unet_config:
|
||||
target: lvdm.modules.networks.openaimodel3d.UNetModel
|
||||
params:
|
||||
in_channels: 8
|
||||
out_channels: 4
|
||||
model_channels: 320
|
||||
attention_resolutions:
|
||||
- 4
|
||||
- 2
|
||||
- 1
|
||||
num_res_blocks: 2
|
||||
channel_mult:
|
||||
- 1
|
||||
- 2
|
||||
- 4
|
||||
- 4
|
||||
dropout: 0.1
|
||||
num_head_channels: 64
|
||||
transformer_depth: 1
|
||||
context_dim: 1024
|
||||
use_linear: true
|
||||
use_checkpoint: True
|
||||
temporal_conv: True
|
||||
temporal_attention: True
|
||||
temporal_selfatt_only: true
|
||||
use_relative_position: false
|
||||
use_causal_attention: False
|
||||
temporal_length: 16
|
||||
addition_attention: true
|
||||
image_cross_attention: true
|
||||
default_fs: 10
|
||||
fs_condition: true
|
||||
|
||||
first_stage_config:
|
||||
target: lvdm.models.autoencoder.AutoencoderKL
|
||||
params:
|
||||
embed_dim: 4
|
||||
monitor: val/rec_loss
|
||||
ddconfig:
|
||||
double_z: True
|
||||
z_channels: 4
|
||||
resolution: 256
|
||||
in_channels: 3
|
||||
out_ch: 3
|
||||
ch: 128
|
||||
ch_mult:
|
||||
- 1
|
||||
- 2
|
||||
- 4
|
||||
- 4
|
||||
num_res_blocks: 2
|
||||
attn_resolutions: []
|
||||
dropout: 0.0
|
||||
lossconfig:
|
||||
target: torch.nn.Identity
|
||||
|
||||
cond_stage_config:
|
||||
target: lvdm.modules.encoders.condition.FrozenOpenCLIPEmbedder
|
||||
params:
|
||||
freeze: true
|
||||
layer: "penultimate"
|
||||
|
||||
img_cond_stage_config:
|
||||
target: lvdm.modules.encoders.condition.FrozenOpenCLIPImageEmbedderV2
|
||||
params:
|
||||
freeze: true
|
||||
|
||||
image_proj_stage_config:
|
||||
target: lvdm.modules.encoders.resampler.Resampler
|
||||
params:
|
||||
dim: 1024
|
||||
depth: 4
|
||||
dim_head: 64
|
||||
heads: 12
|
||||
num_queries: 16
|
||||
embedding_dim: 1280
|
||||
output_dim: 1024
|
||||
ff_mult: 4
|
||||
video_length: 16
|
||||
Vendored
+7
@@ -0,0 +1,7 @@
|
||||
DUSt3R, Copyright (c) 2024-present Naver Corporation, is licensed under the Creative Commons Attribution-NonCommercial-ShareAlike 4.0 license.
|
||||
|
||||
A summary of the CC BY-NC-SA 4.0 license is located here:
|
||||
https://creativecommons.org/licenses/by-nc-sa/4.0/
|
||||
|
||||
The CC BY-NC-SA 4.0 license is located here:
|
||||
https://creativecommons.org/licenses/by-nc-sa/4.0/legalcode
|
||||
+52
@@ -0,0 +1,52 @@
|
||||
CroCo, Copyright (c) 2022-present Naver Corporation, is licensed under the Creative Commons Attribution-NonCommercial-ShareAlike 4.0 license.
|
||||
|
||||
A summary of the CC BY-NC-SA 4.0 license is located here:
|
||||
https://creativecommons.org/licenses/by-nc-sa/4.0/
|
||||
|
||||
The CC BY-NC-SA 4.0 license is located here:
|
||||
https://creativecommons.org/licenses/by-nc-sa/4.0/legalcode
|
||||
|
||||
|
||||
SEE NOTICE BELOW WITH RESPECT TO THE FILE: models/pos_embed.py, models/blocks.py
|
||||
|
||||
***************************
|
||||
|
||||
NOTICE WITH RESPECT TO THE FILE: models/pos_embed.py
|
||||
|
||||
This software is being redistributed in a modifiled form. The original form is available here:
|
||||
|
||||
https://github.com/facebookresearch/mae/blob/main/util/pos_embed.py
|
||||
|
||||
This software in this file incorporates parts of the following software available here:
|
||||
|
||||
Transformer: https://github.com/tensorflow/models/blob/master/official/legacy/transformer/model_utils.py
|
||||
available under the following license: https://github.com/tensorflow/models/blob/master/LICENSE
|
||||
|
||||
MoCo v3: https://github.com/facebookresearch/moco-v3
|
||||
available under the following license: https://github.com/facebookresearch/moco-v3/blob/main/LICENSE
|
||||
|
||||
DeiT: https://github.com/facebookresearch/deit
|
||||
available under the following license: https://github.com/facebookresearch/deit/blob/main/LICENSE
|
||||
|
||||
|
||||
ORIGINAL COPYRIGHT NOTICE AND PERMISSION NOTICE AVAILABLE HERE IS REPRODUCE BELOW:
|
||||
|
||||
https://github.com/facebookresearch/mae/blob/main/LICENSE
|
||||
|
||||
Attribution-NonCommercial 4.0 International
|
||||
|
||||
***************************
|
||||
|
||||
NOTICE WITH RESPECT TO THE FILE: models/blocks.py
|
||||
|
||||
This software is being redistributed in a modifiled form. The original form is available here:
|
||||
|
||||
https://github.com/rwightman/pytorch-image-models
|
||||
|
||||
ORIGINAL COPYRIGHT NOTICE AND PERMISSION NOTICE AVAILABLE HERE IS REPRODUCE BELOW:
|
||||
|
||||
https://github.com/rwightman/pytorch-image-models/blob/master/LICENSE
|
||||
|
||||
Apache License
|
||||
Version 2.0, January 2004
|
||||
http://www.apache.org/licenses/
|
||||
+21
@@ -0,0 +1,21 @@
|
||||
CroCo
|
||||
Copyright 2022-present NAVER Corp.
|
||||
|
||||
This project contains subcomponents with separate copyright notices and license terms.
|
||||
Your use of the source code for these subcomponents is subject to the terms and conditions of the following licenses.
|
||||
|
||||
====
|
||||
|
||||
facebookresearch/mae
|
||||
https://github.com/facebookresearch/mae
|
||||
|
||||
Attribution-NonCommercial 4.0 International
|
||||
|
||||
====
|
||||
|
||||
rwightman/pytorch-image-models
|
||||
https://github.com/rwightman/pytorch-image-models
|
||||
|
||||
Apache License
|
||||
Version 2.0, January 2004
|
||||
http://www.apache.org/licenses/
|
||||
+124
@@ -0,0 +1,124 @@
|
||||
# CroCo + CroCo v2 / CroCo-Stereo / CroCo-Flow
|
||||
|
||||
[[`CroCo arXiv`](https://arxiv.org/abs/2210.10716)] [[`CroCo v2 arXiv`](https://arxiv.org/abs/2211.10408)] [[`project page and demo`](https://croco.europe.naverlabs.com/)]
|
||||
|
||||
This repository contains the code for our CroCo model presented in our NeurIPS'22 paper [CroCo: Self-Supervised Pre-training for 3D Vision Tasks by Cross-View Completion](https://openreview.net/pdf?id=wZEfHUM5ri) and its follow-up extension published at ICCV'23 [Improved Cross-view Completion Pre-training for Stereo Matching and Optical Flow](https://openaccess.thecvf.com/content/ICCV2023/html/Weinzaepfel_CroCo_v2_Improved_Cross-view_Completion_Pre-training_for_Stereo_Matching_and_ICCV_2023_paper.html), refered to as CroCo v2:
|
||||
|
||||

|
||||
|
||||
```bibtex
|
||||
@inproceedings{croco,
|
||||
title={{CroCo: Self-Supervised Pre-training for 3D Vision Tasks by Cross-View Completion}},
|
||||
author={{Weinzaepfel, Philippe and Leroy, Vincent and Lucas, Thomas and Br\'egier, Romain and Cabon, Yohann and Arora, Vaibhav and Antsfeld, Leonid and Chidlovskii, Boris and Csurka, Gabriela and Revaud J\'er\^ome}},
|
||||
booktitle={{NeurIPS}},
|
||||
year={2022}
|
||||
}
|
||||
|
||||
@inproceedings{croco_v2,
|
||||
title={{CroCo v2: Improved Cross-view Completion Pre-training for Stereo Matching and Optical Flow}},
|
||||
author={Weinzaepfel, Philippe and Lucas, Thomas and Leroy, Vincent and Cabon, Yohann and Arora, Vaibhav and Br{\'e}gier, Romain and Csurka, Gabriela and Antsfeld, Leonid and Chidlovskii, Boris and Revaud, J{\'e}r{\^o}me},
|
||||
booktitle={ICCV},
|
||||
year={2023}
|
||||
}
|
||||
```
|
||||
|
||||
## License
|
||||
|
||||
The code is distributed under the CC BY-NC-SA 4.0 License. See [LICENSE](LICENSE) for more information.
|
||||
Some components are based on code from [MAE](https://github.com/facebookresearch/mae) released under the CC BY-NC-SA 4.0 License and [timm](https://github.com/rwightman/pytorch-image-models) released under the Apache 2.0 License.
|
||||
Some components for stereo matching and optical flow are based on code from [unimatch](https://github.com/autonomousvision/unimatch) released under the MIT license.
|
||||
|
||||
## Preparation
|
||||
|
||||
1. Install dependencies on a machine with a NVidia GPU using e.g. conda. Note that `habitat-sim` is required only for the interactive demo and the synthetic pre-training data generation. If you don't plan to use it, you can ignore the line installing it and use a more recent python version.
|
||||
|
||||
```bash
|
||||
conda create -n croco python=3.7 cmake=3.14.0
|
||||
conda activate croco
|
||||
conda install habitat-sim headless -c conda-forge -c aihabitat
|
||||
conda install pytorch torchvision -c pytorch
|
||||
conda install notebook ipykernel matplotlib
|
||||
conda install ipywidgets widgetsnbextension
|
||||
conda install scikit-learn tqdm quaternion opencv # only for pretraining / habitat data generation
|
||||
|
||||
```
|
||||
|
||||
2. Compile cuda kernels for RoPE
|
||||
|
||||
CroCo v2 relies on RoPE positional embeddings for which you need to compile some cuda kernels.
|
||||
```bash
|
||||
cd models/curope/
|
||||
python setup.py build_ext --inplace
|
||||
cd ../../
|
||||
```
|
||||
|
||||
This can be a bit long as we compile for all cuda architectures, feel free to update L9 of `models/curope/setup.py` to compile for specific architectures only.
|
||||
You might also need to set the environment `CUDA_HOME` in case you use a custom cuda installation.
|
||||
|
||||
In case you cannot provide, we also provide a slow pytorch version, which will be automatically loaded.
|
||||
|
||||
3. Download pre-trained model
|
||||
|
||||
We provide several pre-trained models:
|
||||
|
||||
| modelname | pre-training data | pos. embed. | Encoder | Decoder |
|
||||
|------------------------------------------------------------------------------------------------------------------------------------|-------------------|-------------|---------|---------|
|
||||
| [`CroCo.pth`](https://download.europe.naverlabs.com/ComputerVision/CroCo/CroCo.pth) | Habitat | cosine | ViT-B | Small |
|
||||
| [`CroCo_V2_ViTBase_SmallDecoder.pth`](https://download.europe.naverlabs.com/ComputerVision/CroCo/CroCo_V2_ViTBase_SmallDecoder.pth) | Habitat + real | RoPE | ViT-B | Small |
|
||||
| [`CroCo_V2_ViTBase_BaseDecoder.pth`](https://download.europe.naverlabs.com/ComputerVision/CroCo/CroCo_V2_ViTBase_BaseDecoder.pth) | Habitat + real | RoPE | ViT-B | Base |
|
||||
| [`CroCo_V2_ViTLarge_BaseDecoder.pth`](https://download.europe.naverlabs.com/ComputerVision/CroCo/CroCo_V2_ViTLarge_BaseDecoder.pth) | Habitat + real | RoPE | ViT-L | Base |
|
||||
|
||||
To download a specific model, i.e., the first one (`CroCo.pth`)
|
||||
```bash
|
||||
mkdir -p pretrained_models/
|
||||
wget https://download.europe.naverlabs.com/ComputerVision/CroCo/CroCo.pth -P pretrained_models/
|
||||
```
|
||||
|
||||
## Reconstruction example
|
||||
|
||||
Simply run after downloading the `CroCo_V2_ViTLarge_BaseDecoder` pretrained model (or update the corresponding line in `demo.py`)
|
||||
```bash
|
||||
python demo.py
|
||||
```
|
||||
|
||||
## Interactive demonstration of cross-view completion reconstruction on the Habitat simulator
|
||||
|
||||
First download the test scene from Habitat:
|
||||
```bash
|
||||
python -m habitat_sim.utils.datasets_download --uids habitat_test_scenes --data-path habitat-sim-data/
|
||||
```
|
||||
|
||||
Then, run the Notebook demo `interactive_demo.ipynb`.
|
||||
|
||||
In this demo, you should be able to sample a random reference viewpoint from an [Habitat](https://github.com/facebookresearch/habitat-sim) test scene. Use the sliders to change viewpoint and select a masked target view to reconstruct using CroCo.
|
||||
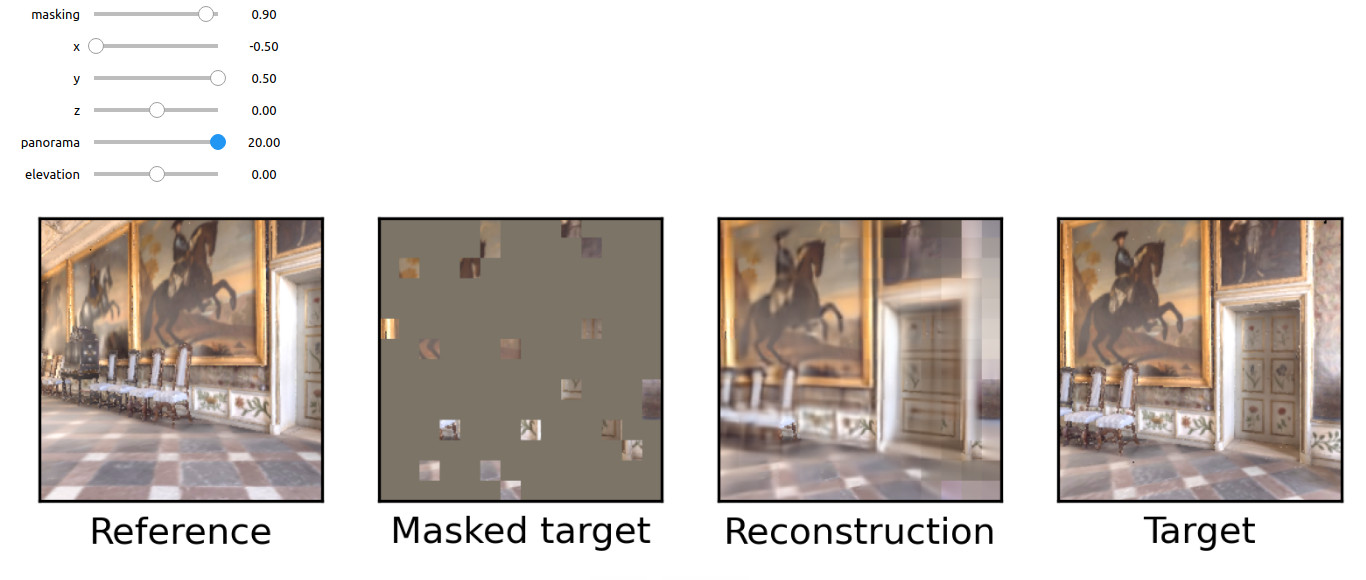
|
||||
|
||||
## Pre-training
|
||||
|
||||
### CroCo
|
||||
|
||||
To pre-train CroCo, please first generate the pre-training data from the Habitat simulator, following the instructions in [datasets/habitat_sim/README.MD](datasets/habitat_sim/README.MD) and then run the following command:
|
||||
```
|
||||
torchrun --nproc_per_node=4 pretrain.py --output_dir ./output/pretraining/
|
||||
```
|
||||
|
||||
Our CroCo pre-training was launched on a single server with 4 GPUs.
|
||||
It should take around 10 days with A100 or 15 days with V100 to do the 400 pre-training epochs, but decent performances are obtained earlier in training.
|
||||
Note that, while the code contains the same scaling rule of the learning rate as MAE when changing the effective batch size, we did not experimented if it is valid in our case.
|
||||
The first run can take a few minutes to start, to parse all available pre-training pairs.
|
||||
|
||||
### CroCo v2
|
||||
|
||||
For CroCo v2 pre-training, in addition to the generation of the pre-training data from the Habitat simulator above, please pre-extract the crops from the real datasets following the instructions in [datasets/crops/README.MD](datasets/crops/README.MD).
|
||||
Then, run the following command for the largest model (ViT-L encoder, Base decoder):
|
||||
```
|
||||
torchrun --nproc_per_node=8 pretrain.py --model "CroCoNet(enc_embed_dim=1024, enc_depth=24, enc_num_heads=16, dec_embed_dim=768, dec_num_heads=12, dec_depth=12, pos_embed='RoPE100')" --dataset "habitat_release+ARKitScenes+MegaDepth+3DStreetView+IndoorVL" --warmup_epochs 12 --max_epoch 125 --epochs 250 --amp 0 --keep_freq 5 --output_dir ./output/pretraining_crocov2/
|
||||
```
|
||||
|
||||
Our CroCo v2 pre-training was launched on a single server with 8 GPUs for the largest model, and on a single server with 4 GPUs for the smaller ones, keeping a batch size of 64 per gpu in all cases.
|
||||
The largest model should take around 12 days on A100.
|
||||
Note that, while the code contains the same scaling rule of the learning rate as MAE when changing the effective batch size, we did not experimented if it is valid in our case.
|
||||
|
||||
## Stereo matching and Optical flow downstream tasks
|
||||
|
||||
For CroCo-Stereo and CroCo-Flow, please refer to [stereoflow/README.MD](stereoflow/README.MD).
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 110 KiB |

Binary file not shown.
|
After Width: | Height: | Size: 107 KiB |
BIN

Binary file not shown.
|
After Width: | Height: | Size: 73 KiB |
@@ -0,0 +1,191 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "9bca0f41",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Simple inference example with CroCo-Stereo or CroCo-Flow"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "80653ef7",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Copyright (C) 2022-present Naver Corporation. All rights reserved.\n",
|
||||
"# Licensed under CC BY-NC-SA 4.0 (non-commercial use only)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "4f033862",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"First download the model(s) of your choice by running\n",
|
||||
"```\n",
|
||||
"bash stereoflow/download_model.sh crocostereo.pth\n",
|
||||
"bash stereoflow/download_model.sh crocoflow.pth\n",
|
||||
"```"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "1fb2e392",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import torch\n",
|
||||
"use_gpu = torch.cuda.is_available() and torch.cuda.device_count()>0\n",
|
||||
"device = torch.device('cuda:0' if use_gpu else 'cpu')\n",
|
||||
"import matplotlib.pylab as plt"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "e0e25d77",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from stereoflow.test import _load_model_and_criterion\n",
|
||||
"from stereoflow.engine import tiled_pred\n",
|
||||
"from stereoflow.datasets_stereo import img_to_tensor, vis_disparity\n",
|
||||
"from stereoflow.datasets_flow import flowToColor\n",
|
||||
"tile_overlap=0.7 # recommended value, higher value can be slightly better but slower"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "86a921f5",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"### CroCo-Stereo example"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "64e483cb",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"image1 = np.asarray(Image.open('<path_to_left_image>'))\n",
|
||||
"image2 = np.asarray(Image.open('<path_to_right_image>'))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "f0d04303",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model, _, cropsize, with_conf, task, tile_conf_mode = _load_model_and_criterion('stereoflow_models/crocostereo.pth', None, device)\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "47dc14b5",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"im1 = img_to_tensor(image1).to(device).unsqueeze(0)\n",
|
||||
"im2 = img_to_tensor(image2).to(device).unsqueeze(0)\n",
|
||||
"with torch.inference_mode():\n",
|
||||
" pred, _, _ = tiled_pred(model, None, im1, im2, None, conf_mode=tile_conf_mode, overlap=tile_overlap, crop=cropsize, with_conf=with_conf, return_time=False)\n",
|
||||
"pred = pred.squeeze(0).squeeze(0).cpu().numpy()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "583b9f16",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"plt.imshow(vis_disparity(pred))\n",
|
||||
"plt.axis('off')"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "d2df5d70",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"### CroCo-Flow example"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "9ee257a7",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"image1 = np.asarray(Image.open('<path_to_first_image>'))\n",
|
||||
"image2 = np.asarray(Image.open('<path_to_second_image>'))"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "d5edccf0",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model, _, cropsize, with_conf, task, tile_conf_mode = _load_model_and_criterion('stereoflow_models/crocoflow.pth', None, device)\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "b19692c3",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"im1 = img_to_tensor(image1).to(device).unsqueeze(0)\n",
|
||||
"im2 = img_to_tensor(image2).to(device).unsqueeze(0)\n",
|
||||
"with torch.inference_mode():\n",
|
||||
" pred, _, _ = tiled_pred(model, None, im1, im2, None, conf_mode=tile_conf_mode, overlap=tile_overlap, crop=cropsize, with_conf=with_conf, return_time=False)\n",
|
||||
"pred = pred.squeeze(0).permute(1,2,0).cpu().numpy()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "26f79db3",
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"plt.imshow(flowToColor(pred))\n",
|
||||
"plt.axis('off')"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3 (ipykernel)",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.9.7"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 5
|
||||
}
|
||||
@@ -0,0 +1,104 @@
|
||||
## Generation of crops from the real datasets
|
||||
|
||||
The instructions below allow to generate the crops used for pre-training CroCo v2 from the following real-world datasets: ARKitScenes, MegaDepth, 3DStreetView and IndoorVL.
|
||||
|
||||
### Download the metadata of the crops to generate
|
||||
|
||||
First, download the metadata and put them in `./data/`:
|
||||
```
|
||||
mkdir -p data
|
||||
cd data/
|
||||
wget https://download.europe.naverlabs.com/ComputerVision/CroCo/data/crop_metadata.zip
|
||||
unzip crop_metadata.zip
|
||||
rm crop_metadata.zip
|
||||
cd ..
|
||||
```
|
||||
|
||||
### Prepare the original datasets
|
||||
|
||||
Second, download the original datasets in `./data/original_datasets/`.
|
||||
```
|
||||
mkdir -p data/original_datasets
|
||||
```
|
||||
|
||||
##### ARKitScenes
|
||||
|
||||
Download the `raw` dataset from https://github.com/apple/ARKitScenes/blob/main/DATA.md and put it in `./data/original_datasets/ARKitScenes/`.
|
||||
The resulting file structure should be like:
|
||||
```
|
||||
./data/original_datasets/ARKitScenes/
|
||||
└───Training
|
||||
└───40753679
|
||||
│ │ ultrawide
|
||||
│ │ ...
|
||||
└───40753686
|
||||
│
|
||||
...
|
||||
```
|
||||
|
||||
##### MegaDepth
|
||||
|
||||
Download `MegaDepth v1 Dataset` from https://www.cs.cornell.edu/projects/megadepth/ and put it in `./data/original_datasets/MegaDepth/`.
|
||||
The resulting file structure should be like:
|
||||
|
||||
```
|
||||
./data/original_datasets/MegaDepth/
|
||||
└───0000
|
||||
│ └───images
|
||||
│ │ │ 1000557903_87fa96b8a4_o.jpg
|
||||
│ │ └ ...
|
||||
│ └─── ...
|
||||
└───0001
|
||||
│ │
|
||||
│ └ ...
|
||||
└─── ...
|
||||
```
|
||||
|
||||
##### 3DStreetView
|
||||
|
||||
Download `3D_Street_View` dataset from https://github.com/amir32002/3D_Street_View and put it in `./data/original_datasets/3DStreetView/`.
|
||||
The resulting file structure should be like:
|
||||
|
||||
```
|
||||
./data/original_datasets/3DStreetView/
|
||||
└───dataset_aligned
|
||||
│ └───0002
|
||||
│ │ │ 0000002_0000001_0000002_0000001.jpg
|
||||
│ │ └ ...
|
||||
│ └─── ...
|
||||
└───dataset_unaligned
|
||||
│ └───0003
|
||||
│ │ │ 0000003_0000001_0000002_0000001.jpg
|
||||
│ │ └ ...
|
||||
│ └─── ...
|
||||
```
|
||||
|
||||
##### IndoorVL
|
||||
|
||||
Download the `IndoorVL` datasets using [Kapture](https://github.com/naver/kapture).
|
||||
|
||||
```
|
||||
pip install kapture
|
||||
mkdir -p ./data/original_datasets/IndoorVL
|
||||
cd ./data/original_datasets/IndoorVL
|
||||
kapture_download_dataset.py update
|
||||
kapture_download_dataset.py install "HyundaiDepartmentStore_*"
|
||||
kapture_download_dataset.py install "GangnamStation_*"
|
||||
cd -
|
||||
```
|
||||
|
||||
### Extract the crops
|
||||
|
||||
Now, extract the crops for each of the dataset:
|
||||
```
|
||||
for dataset in ARKitScenes MegaDepth 3DStreetView IndoorVL;
|
||||
do
|
||||
python3 datasets/crops/extract_crops_from_images.py --crops ./data/crop_metadata/${dataset}/crops_release.txt --root-dir ./data/original_datasets/${dataset}/ --output-dir ./data/${dataset}_crops/ --imsize 256 --nthread 8 --max-subdir-levels 5 --ideal-number-pairs-in-dir 500;
|
||||
done
|
||||
```
|
||||
|
||||
##### Note for IndoorVL
|
||||
|
||||
Due to some legal issues, we can only release 144,228 pairs out of the 1,593,689 pairs used in the paper.
|
||||
To account for it in terms of number of pre-training iterations, the pre-training command in this repository uses 125 training epochs including 12 warm-up epochs and learning rate cosine schedule of 250, instead of 100, 10 and 200 respectively.
|
||||
The impact on the performance is negligible.
|
||||
@@ -0,0 +1,159 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# Extracting crops for pre-training
|
||||
# --------------------------------------------------------
|
||||
|
||||
import os
|
||||
import argparse
|
||||
from tqdm import tqdm
|
||||
from PIL import Image
|
||||
import functools
|
||||
from multiprocessing import Pool
|
||||
import math
|
||||
|
||||
|
||||
def arg_parser():
|
||||
parser = argparse.ArgumentParser('Generate cropped image pairs from image crop list')
|
||||
|
||||
parser.add_argument('--crops', type=str, required=True, help='crop file')
|
||||
parser.add_argument('--root-dir', type=str, required=True, help='root directory')
|
||||
parser.add_argument('--output-dir', type=str, required=True, help='output directory')
|
||||
parser.add_argument('--imsize', type=int, default=256, help='size of the crops')
|
||||
parser.add_argument('--nthread', type=int, required=True, help='number of simultaneous threads')
|
||||
parser.add_argument('--max-subdir-levels', type=int, default=5, help='maximum number of subdirectories')
|
||||
parser.add_argument('--ideal-number-pairs-in-dir', type=int, default=500, help='number of pairs stored in a dir')
|
||||
return parser
|
||||
|
||||
|
||||
def main(args):
|
||||
listing_path = os.path.join(args.output_dir, 'listing.txt')
|
||||
|
||||
print(f'Loading list of crops ... ({args.nthread} threads)')
|
||||
crops, num_crops_to_generate = load_crop_file(args.crops)
|
||||
|
||||
print(f'Preparing jobs ({len(crops)} candidate image pairs)...')
|
||||
num_levels = min(math.ceil(math.log(num_crops_to_generate, args.ideal_number_pairs_in_dir)), args.max_subdir_levels)
|
||||
num_pairs_in_dir = math.ceil(num_crops_to_generate ** (1/num_levels))
|
||||
|
||||
jobs = prepare_jobs(crops, num_levels, num_pairs_in_dir)
|
||||
del crops
|
||||
|
||||
os.makedirs(args.output_dir, exist_ok=True)
|
||||
mmap = Pool(args.nthread).imap_unordered if args.nthread > 1 else map
|
||||
call = functools.partial(save_image_crops, args)
|
||||
|
||||
print(f"Generating cropped images to {args.output_dir} ...")
|
||||
with open(listing_path, 'w') as listing:
|
||||
listing.write('# pair_path\n')
|
||||
for results in tqdm(mmap(call, jobs), total=len(jobs)):
|
||||
for path in results:
|
||||
listing.write(f'{path}\n')
|
||||
print('Finished writing listing to', listing_path)
|
||||
|
||||
|
||||
def load_crop_file(path):
|
||||
data = open(path).read().splitlines()
|
||||
pairs = []
|
||||
num_crops_to_generate = 0
|
||||
for line in tqdm(data):
|
||||
if line.startswith('#'):
|
||||
continue
|
||||
line = line.split(', ')
|
||||
if len(line) < 8:
|
||||
img1, img2, rotation = line
|
||||
pairs.append((img1, img2, int(rotation), []))
|
||||
else:
|
||||
l1, r1, t1, b1, l2, r2, t2, b2 = map(int, line)
|
||||
rect1, rect2 = (l1, t1, r1, b1), (l2, t2, r2, b2)
|
||||
pairs[-1][-1].append((rect1, rect2))
|
||||
num_crops_to_generate += 1
|
||||
return pairs, num_crops_to_generate
|
||||
|
||||
|
||||
def prepare_jobs(pairs, num_levels, num_pairs_in_dir):
|
||||
jobs = []
|
||||
powers = [num_pairs_in_dir**level for level in reversed(range(num_levels))]
|
||||
|
||||
def get_path(idx):
|
||||
idx_array = []
|
||||
d = idx
|
||||
for level in range(num_levels - 1):
|
||||
idx_array.append(idx // powers[level])
|
||||
idx = idx % powers[level]
|
||||
idx_array.append(d)
|
||||
return '/'.join(map(lambda x: hex(x)[2:], idx_array))
|
||||
|
||||
idx = 0
|
||||
for pair_data in tqdm(pairs):
|
||||
img1, img2, rotation, crops = pair_data
|
||||
if -60 <= rotation and rotation <= 60:
|
||||
rotation = 0 # most likely not a true rotation
|
||||
paths = [get_path(idx + k) for k in range(len(crops))]
|
||||
idx += len(crops)
|
||||
jobs.append(((img1, img2), rotation, crops, paths))
|
||||
return jobs
|
||||
|
||||
|
||||
def load_image(path):
|
||||
try:
|
||||
return Image.open(path).convert('RGB')
|
||||
except Exception as e:
|
||||
print('skipping', path, e)
|
||||
raise OSError()
|
||||
|
||||
|
||||
def save_image_crops(args, data):
|
||||
# load images
|
||||
img_pair, rot, crops, paths = data
|
||||
try:
|
||||
img1, img2 = [load_image(os.path.join(args.root_dir, impath)) for impath in img_pair]
|
||||
except OSError as e:
|
||||
return []
|
||||
|
||||
def area(sz):
|
||||
return sz[0] * sz[1]
|
||||
|
||||
tgt_size = (args.imsize, args.imsize)
|
||||
|
||||
def prepare_crop(img, rect, rot=0):
|
||||
# actual crop
|
||||
img = img.crop(rect)
|
||||
|
||||
# resize to desired size
|
||||
interp = Image.Resampling.LANCZOS if area(img.size) > 4*area(tgt_size) else Image.Resampling.BICUBIC
|
||||
img = img.resize(tgt_size, resample=interp)
|
||||
|
||||
# rotate the image
|
||||
rot90 = (round(rot/90) % 4) * 90
|
||||
if rot90 == 90:
|
||||
img = img.transpose(Image.Transpose.ROTATE_90)
|
||||
elif rot90 == 180:
|
||||
img = img.transpose(Image.Transpose.ROTATE_180)
|
||||
elif rot90 == 270:
|
||||
img = img.transpose(Image.Transpose.ROTATE_270)
|
||||
return img
|
||||
|
||||
results = []
|
||||
for (rect1, rect2), path in zip(crops, paths):
|
||||
crop1 = prepare_crop(img1, rect1)
|
||||
crop2 = prepare_crop(img2, rect2, rot)
|
||||
|
||||
fullpath1 = os.path.join(args.output_dir, path+'_1.jpg')
|
||||
fullpath2 = os.path.join(args.output_dir, path+'_2.jpg')
|
||||
os.makedirs(os.path.dirname(fullpath1), exist_ok=True)
|
||||
|
||||
assert not os.path.isfile(fullpath1), fullpath1
|
||||
assert not os.path.isfile(fullpath2), fullpath2
|
||||
crop1.save(fullpath1)
|
||||
crop2.save(fullpath2)
|
||||
results.append(path)
|
||||
|
||||
return results
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
args = arg_parser().parse_args()
|
||||
main(args)
|
||||
|
||||
@@ -0,0 +1,76 @@
|
||||
## Generation of synthetic image pairs using Habitat-Sim
|
||||
|
||||
These instructions allow to generate pre-training pairs from the Habitat simulator.
|
||||
As we did not save metadata of the pairs used in the original paper, they are not strictly the same, but these data use the same setting and are equivalent.
|
||||
|
||||
### Download Habitat-Sim scenes
|
||||
Download Habitat-Sim scenes:
|
||||
- Download links can be found here: https://github.com/facebookresearch/habitat-sim/blob/main/DATASETS.md
|
||||
- We used scenes from the HM3D, habitat-test-scenes, Replica, ReplicaCad and ScanNet datasets.
|
||||
- Please put the scenes under `./data/habitat-sim-data/scene_datasets/` following the structure below, or update manually paths in `paths.py`.
|
||||
```
|
||||
./data/
|
||||
└──habitat-sim-data/
|
||||
└──scene_datasets/
|
||||
├──hm3d/
|
||||
├──gibson/
|
||||
├──habitat-test-scenes/
|
||||
├──replica_cad_baked_lighting/
|
||||
├──replica_cad/
|
||||
├──ReplicaDataset/
|
||||
└──scannet/
|
||||
```
|
||||
|
||||
### Image pairs generation
|
||||
We provide metadata to generate reproducible images pairs for pretraining and validation.
|
||||
Experiments described in the paper used similar data, but whose generation was not reproducible at the time.
|
||||
|
||||
Specifications:
|
||||
- 256x256 resolution images, with 60 degrees field of view .
|
||||
- Up to 1000 image pairs per scene.
|
||||
- Number of scenes considered/number of images pairs per dataset:
|
||||
- Scannet: 1097 scenes / 985 209 pairs
|
||||
- HM3D:
|
||||
- hm3d/train: 800 / 800k pairs
|
||||
- hm3d/val: 100 scenes / 100k pairs
|
||||
- hm3d/minival: 10 scenes / 10k pairs
|
||||
- habitat-test-scenes: 3 scenes / 3k pairs
|
||||
- replica_cad_baked_lighting: 13 scenes / 13k pairs
|
||||
|
||||
- Scenes from hm3d/val and hm3d/minival pairs were not used for the pre-training but kept for validation purposes.
|
||||
|
||||
Download metadata and extract it:
|
||||
```bash
|
||||
mkdir -p data/habitat_release_metadata/
|
||||
cd data/habitat_release_metadata/
|
||||
wget https://download.europe.naverlabs.com/ComputerVision/CroCo/data/habitat_release_metadata/multiview_habitat_metadata.tar.gz
|
||||
tar -xvf multiview_habitat_metadata.tar.gz
|
||||
cd ../..
|
||||
# Location of the metadata
|
||||
METADATA_DIR="./data/habitat_release_metadata/multiview_habitat_metadata"
|
||||
```
|
||||
|
||||
Generate image pairs from metadata:
|
||||
- The following command will print a list of commandlines to generate image pairs for each scene:
|
||||
```bash
|
||||
# Target output directory
|
||||
PAIRS_DATASET_DIR="./data/habitat_release/"
|
||||
python datasets/habitat_sim/generate_from_metadata_files.py --input_dir=$METADATA_DIR --output_dir=$PAIRS_DATASET_DIR
|
||||
```
|
||||
- One can launch multiple of such commands in parallel e.g. using GNU Parallel:
|
||||
```bash
|
||||
python datasets/habitat_sim/generate_from_metadata_files.py --input_dir=$METADATA_DIR --output_dir=$PAIRS_DATASET_DIR | parallel -j 16
|
||||
```
|
||||
|
||||
## Metadata generation
|
||||
|
||||
Image pairs were randomly sampled using the following commands, whose outputs contain randomness and are thus not exactly reproducible:
|
||||
```bash
|
||||
# Print commandlines to generate image pairs from the different scenes available.
|
||||
PAIRS_DATASET_DIR=MY_CUSTOM_PATH
|
||||
python datasets/habitat_sim/generate_multiview_images.py --list_commands --output_dir=$PAIRS_DATASET_DIR
|
||||
|
||||
# Once a dataset is generated, pack metadata files for reproducibility.
|
||||
METADATA_DIR=MY_CUSTON_PATH
|
||||
python datasets/habitat_sim/pack_metadata_files.py $PAIRS_DATASET_DIR $METADATA_DIR
|
||||
```
|
||||
+92
@@ -0,0 +1,92 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
"""
|
||||
Script to generate image pairs for a given scene reproducing poses provided in a metadata file.
|
||||
"""
|
||||
import os
|
||||
from datasets.habitat_sim.multiview_habitat_sim_generator import MultiviewHabitatSimGenerator
|
||||
from datasets.habitat_sim.paths import SCENES_DATASET
|
||||
import argparse
|
||||
import quaternion
|
||||
import PIL.Image
|
||||
import cv2
|
||||
import json
|
||||
from tqdm import tqdm
|
||||
|
||||
def generate_multiview_images_from_metadata(metadata_filename,
|
||||
output_dir,
|
||||
overload_params = dict(),
|
||||
scene_datasets_paths=None,
|
||||
exist_ok=False):
|
||||
"""
|
||||
Generate images from a metadata file for reproducibility purposes.
|
||||
"""
|
||||
# Reorder paths by decreasing label length, to avoid collisions when testing if a string by such label
|
||||
if scene_datasets_paths is not None:
|
||||
scene_datasets_paths = dict(sorted(scene_datasets_paths.items(), key= lambda x: len(x[0]), reverse=True))
|
||||
|
||||
with open(metadata_filename, 'r') as f:
|
||||
input_metadata = json.load(f)
|
||||
metadata = dict()
|
||||
for key, value in input_metadata.items():
|
||||
# Optionally replace some paths
|
||||
if key in ("scene_dataset_config_file", "scene", "navmesh") and value != "":
|
||||
if scene_datasets_paths is not None:
|
||||
for dataset_label, dataset_path in scene_datasets_paths.items():
|
||||
if value.startswith(dataset_label):
|
||||
value = os.path.normpath(os.path.join(dataset_path, os.path.relpath(value, dataset_label)))
|
||||
break
|
||||
metadata[key] = value
|
||||
|
||||
# Overload some parameters
|
||||
for key, value in overload_params.items():
|
||||
metadata[key] = value
|
||||
|
||||
generation_entries = dict([(key, value) for key, value in metadata.items() if not (key in ('multiviews', 'output_dir', 'generate_depth'))])
|
||||
generate_depth = metadata["generate_depth"]
|
||||
|
||||
os.makedirs(output_dir, exist_ok=exist_ok)
|
||||
|
||||
generator = MultiviewHabitatSimGenerator(**generation_entries)
|
||||
|
||||
# Generate views
|
||||
for idx_label, data in tqdm(metadata['multiviews'].items()):
|
||||
positions = data["positions"]
|
||||
orientations = data["orientations"]
|
||||
n = len(positions)
|
||||
for oidx in range(n):
|
||||
observation = generator.render_viewpoint(positions[oidx], quaternion.from_float_array(orientations[oidx]))
|
||||
observation_label = f"{oidx + 1}" # Leonid is indexing starting from 1
|
||||
# Color image saved using PIL
|
||||
img = PIL.Image.fromarray(observation['color'][:,:,:3])
|
||||
filename = os.path.join(output_dir, f"{idx_label}_{observation_label}.jpeg")
|
||||
img.save(filename)
|
||||
if generate_depth:
|
||||
# Depth image as EXR file
|
||||
filename = os.path.join(output_dir, f"{idx_label}_{observation_label}_depth.exr")
|
||||
cv2.imwrite(filename, observation['depth'], [cv2.IMWRITE_EXR_TYPE, cv2.IMWRITE_EXR_TYPE_HALF])
|
||||
# Camera parameters
|
||||
camera_params = dict([(key, observation[key].tolist()) for key in ("camera_intrinsics", "R_cam2world", "t_cam2world")])
|
||||
filename = os.path.join(output_dir, f"{idx_label}_{observation_label}_camera_params.json")
|
||||
with open(filename, "w") as f:
|
||||
json.dump(camera_params, f)
|
||||
# Save metadata
|
||||
with open(os.path.join(output_dir, "metadata.json"), "w") as f:
|
||||
json.dump(metadata, f)
|
||||
|
||||
generator.close()
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--metadata_filename", required=True)
|
||||
parser.add_argument("--output_dir", required=True)
|
||||
args = parser.parse_args()
|
||||
|
||||
generate_multiview_images_from_metadata(metadata_filename=args.metadata_filename,
|
||||
output_dir=args.output_dir,
|
||||
scene_datasets_paths=SCENES_DATASET,
|
||||
overload_params=dict(),
|
||||
exist_ok=True)
|
||||
|
||||
|
||||
+27
@@ -0,0 +1,27 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
"""
|
||||
Script generating commandlines to generate image pairs from metadata files.
|
||||
"""
|
||||
import os
|
||||
import glob
|
||||
from tqdm import tqdm
|
||||
import argparse
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--input_dir", required=True)
|
||||
parser.add_argument("--output_dir", required=True)
|
||||
parser.add_argument("--prefix", default="", help="Commanline prefix, useful e.g. to setup environment.")
|
||||
args = parser.parse_args()
|
||||
|
||||
input_metadata_filenames = glob.iglob(f"{args.input_dir}/**/metadata.json", recursive=True)
|
||||
|
||||
for metadata_filename in tqdm(input_metadata_filenames):
|
||||
output_dir = os.path.join(args.output_dir, os.path.relpath(os.path.dirname(metadata_filename), args.input_dir))
|
||||
# Do not process the scene if the metadata file already exists
|
||||
if os.path.exists(os.path.join(output_dir, "metadata.json")):
|
||||
continue
|
||||
commandline = f"{args.prefix}python datasets/habitat_sim/generate_from_metadata.py --metadata_filename={metadata_filename} --output_dir={output_dir}"
|
||||
print(commandline)
|
||||
+177
@@ -0,0 +1,177 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
import os
|
||||
from tqdm import tqdm
|
||||
import argparse
|
||||
import PIL.Image
|
||||
import numpy as np
|
||||
import json
|
||||
from datasets.habitat_sim.multiview_habitat_sim_generator import MultiviewHabitatSimGenerator, NoNaviguableSpaceError
|
||||
from datasets.habitat_sim.paths import list_scenes_available
|
||||
import cv2
|
||||
import quaternion
|
||||
import shutil
|
||||
|
||||
def generate_multiview_images_for_scene(scene_dataset_config_file,
|
||||
scene,
|
||||
navmesh,
|
||||
output_dir,
|
||||
views_count,
|
||||
size,
|
||||
exist_ok=False,
|
||||
generate_depth=False,
|
||||
**kwargs):
|
||||
"""
|
||||
Generate tuples of overlapping views for a given scene.
|
||||
generate_depth: generate depth images and camera parameters.
|
||||
"""
|
||||
if os.path.exists(output_dir) and not exist_ok:
|
||||
print(f"Scene {scene}: data already generated. Ignoring generation.")
|
||||
return
|
||||
try:
|
||||
print(f"Scene {scene}: {size} multiview acquisitions to generate...")
|
||||
os.makedirs(output_dir, exist_ok=exist_ok)
|
||||
|
||||
metadata_filename = os.path.join(output_dir, "metadata.json")
|
||||
|
||||
metadata_template = dict(scene_dataset_config_file=scene_dataset_config_file,
|
||||
scene=scene,
|
||||
navmesh=navmesh,
|
||||
views_count=views_count,
|
||||
size=size,
|
||||
generate_depth=generate_depth,
|
||||
**kwargs)
|
||||
metadata_template["multiviews"] = dict()
|
||||
|
||||
if os.path.exists(metadata_filename):
|
||||
print("Metadata file already exists:", metadata_filename)
|
||||
print("Loading already generated metadata file...")
|
||||
with open(metadata_filename, "r") as f:
|
||||
metadata = json.load(f)
|
||||
|
||||
for key in metadata_template.keys():
|
||||
if key != "multiviews":
|
||||
assert metadata_template[key] == metadata[key], f"existing file is inconsistent with the input parameters:\nKey: {key}\nmetadata: {metadata[key]}\ntemplate: {metadata_template[key]}."
|
||||
else:
|
||||
print("No temporary file found. Starting generation from scratch...")
|
||||
metadata = metadata_template
|
||||
|
||||
starting_id = len(metadata["multiviews"])
|
||||
print(f"Starting generation from index {starting_id}/{size}...")
|
||||
if starting_id >= size:
|
||||
print("Generation already done.")
|
||||
return
|
||||
|
||||
generator = MultiviewHabitatSimGenerator(scene_dataset_config_file=scene_dataset_config_file,
|
||||
scene=scene,
|
||||
navmesh=navmesh,
|
||||
views_count = views_count,
|
||||
size = size,
|
||||
**kwargs)
|
||||
|
||||
for idx in tqdm(range(starting_id, size)):
|
||||
# Generate / re-generate the observations
|
||||
try:
|
||||
data = generator[idx]
|
||||
observations = data["observations"]
|
||||
positions = data["positions"]
|
||||
orientations = data["orientations"]
|
||||
|
||||
idx_label = f"{idx:08}"
|
||||
for oidx, observation in enumerate(observations):
|
||||
observation_label = f"{oidx + 1}" # Leonid is indexing starting from 1
|
||||
# Color image saved using PIL
|
||||
img = PIL.Image.fromarray(observation['color'][:,:,:3])
|
||||
filename = os.path.join(output_dir, f"{idx_label}_{observation_label}.jpeg")
|
||||
img.save(filename)
|
||||
if generate_depth:
|
||||
# Depth image as EXR file
|
||||
filename = os.path.join(output_dir, f"{idx_label}_{observation_label}_depth.exr")
|
||||
cv2.imwrite(filename, observation['depth'], [cv2.IMWRITE_EXR_TYPE, cv2.IMWRITE_EXR_TYPE_HALF])
|
||||
# Camera parameters
|
||||
camera_params = dict([(key, observation[key].tolist()) for key in ("camera_intrinsics", "R_cam2world", "t_cam2world")])
|
||||
filename = os.path.join(output_dir, f"{idx_label}_{observation_label}_camera_params.json")
|
||||
with open(filename, "w") as f:
|
||||
json.dump(camera_params, f)
|
||||
metadata["multiviews"][idx_label] = {"positions": positions.tolist(),
|
||||
"orientations": orientations.tolist(),
|
||||
"covisibility_ratios": data["covisibility_ratios"].tolist(),
|
||||
"valid_fractions": data["valid_fractions"].tolist(),
|
||||
"pairwise_visibility_ratios": data["pairwise_visibility_ratios"].tolist()}
|
||||
except RecursionError:
|
||||
print("Recursion error: unable to sample observations for this scene. We will stop there.")
|
||||
break
|
||||
|
||||
# Regularly save a temporary metadata file, in case we need to restart the generation
|
||||
if idx % 10 == 0:
|
||||
with open(metadata_filename, "w") as f:
|
||||
json.dump(metadata, f)
|
||||
|
||||
# Save metadata
|
||||
with open(metadata_filename, "w") as f:
|
||||
json.dump(metadata, f)
|
||||
|
||||
generator.close()
|
||||
except NoNaviguableSpaceError:
|
||||
pass
|
||||
|
||||
def create_commandline(scene_data, generate_depth, exist_ok=False):
|
||||
"""
|
||||
Create a commandline string to generate a scene.
|
||||
"""
|
||||
def my_formatting(val):
|
||||
if val is None or val == "":
|
||||
return '""'
|
||||
else:
|
||||
return val
|
||||
commandline = f"""python {__file__} --scene {my_formatting(scene_data.scene)}
|
||||
--scene_dataset_config_file {my_formatting(scene_data.scene_dataset_config_file)}
|
||||
--navmesh {my_formatting(scene_data.navmesh)}
|
||||
--output_dir {my_formatting(scene_data.output_dir)}
|
||||
--generate_depth {int(generate_depth)}
|
||||
--exist_ok {int(exist_ok)}
|
||||
"""
|
||||
commandline = " ".join(commandline.split())
|
||||
return commandline
|
||||
|
||||
if __name__ == "__main__":
|
||||
os.umask(2)
|
||||
|
||||
parser = argparse.ArgumentParser(description="""Example of use -- listing commands to generate data for scenes available:
|
||||
> python datasets/habitat_sim/generate_multiview_habitat_images.py --list_commands
|
||||
""")
|
||||
|
||||
parser.add_argument("--output_dir", type=str, required=True)
|
||||
parser.add_argument("--list_commands", action='store_true', help="list commandlines to run if true")
|
||||
parser.add_argument("--scene", type=str, default="")
|
||||
parser.add_argument("--scene_dataset_config_file", type=str, default="")
|
||||
parser.add_argument("--navmesh", type=str, default="")
|
||||
|
||||
parser.add_argument("--generate_depth", type=int, default=1)
|
||||
parser.add_argument("--exist_ok", type=int, default=0)
|
||||
|
||||
kwargs = dict(resolution=(256,256), hfov=60, views_count = 2, size=1000)
|
||||
|
||||
args = parser.parse_args()
|
||||
generate_depth=bool(args.generate_depth)
|
||||
exist_ok = bool(args.exist_ok)
|
||||
|
||||
if args.list_commands:
|
||||
# Listing scenes available...
|
||||
scenes_data = list_scenes_available(base_output_dir=args.output_dir)
|
||||
|
||||
for scene_data in scenes_data:
|
||||
print(create_commandline(scene_data, generate_depth=generate_depth, exist_ok=exist_ok))
|
||||
else:
|
||||
if args.scene == "" or args.output_dir == "":
|
||||
print("Missing scene or output dir argument!")
|
||||
print(parser.format_help())
|
||||
else:
|
||||
generate_multiview_images_for_scene(scene=args.scene,
|
||||
scene_dataset_config_file = args.scene_dataset_config_file,
|
||||
navmesh = args.navmesh,
|
||||
output_dir = args.output_dir,
|
||||
exist_ok=exist_ok,
|
||||
generate_depth=generate_depth,
|
||||
**kwargs)
|
||||
+390
@@ -0,0 +1,390 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
import os
|
||||
import numpy as np
|
||||
import quaternion
|
||||
import habitat_sim
|
||||
import json
|
||||
from sklearn.neighbors import NearestNeighbors
|
||||
import cv2
|
||||
|
||||
# OpenCV to habitat camera convention transformation
|
||||
R_OPENCV2HABITAT = np.stack((habitat_sim.geo.RIGHT, -habitat_sim.geo.UP, habitat_sim.geo.FRONT), axis=0)
|
||||
R_HABITAT2OPENCV = R_OPENCV2HABITAT.T
|
||||
DEG2RAD = np.pi / 180
|
||||
|
||||
def compute_camera_intrinsics(height, width, hfov):
|
||||
f = width/2 / np.tan(hfov/2 * np.pi/180)
|
||||
cu, cv = width/2, height/2
|
||||
return f, cu, cv
|
||||
|
||||
def compute_camera_pose_opencv_convention(camera_position, camera_orientation):
|
||||
R_cam2world = quaternion.as_rotation_matrix(camera_orientation) @ R_OPENCV2HABITAT
|
||||
t_cam2world = np.asarray(camera_position)
|
||||
return R_cam2world, t_cam2world
|
||||
|
||||
def compute_pointmap(depthmap, hfov):
|
||||
""" Compute a HxWx3 pointmap in camera frame from a HxW depth map."""
|
||||
height, width = depthmap.shape
|
||||
f, cu, cv = compute_camera_intrinsics(height, width, hfov)
|
||||
# Cast depth map to point
|
||||
z_cam = depthmap
|
||||
u, v = np.meshgrid(range(width), range(height))
|
||||
x_cam = (u - cu) / f * z_cam
|
||||
y_cam = (v - cv) / f * z_cam
|
||||
X_cam = np.stack((x_cam, y_cam, z_cam), axis=-1)
|
||||
return X_cam
|
||||
|
||||
def compute_pointcloud(depthmap, hfov, camera_position, camera_rotation):
|
||||
"""Return a 3D point cloud corresponding to valid pixels of the depth map"""
|
||||
R_cam2world, t_cam2world = compute_camera_pose_opencv_convention(camera_position, camera_rotation)
|
||||
|
||||
X_cam = compute_pointmap(depthmap=depthmap, hfov=hfov)
|
||||
valid_mask = (X_cam[:,:,2] != 0.0)
|
||||
|
||||
X_cam = X_cam.reshape(-1, 3)[valid_mask.flatten()]
|
||||
X_world = X_cam @ R_cam2world.T + t_cam2world.reshape(1, 3)
|
||||
return X_world
|
||||
|
||||
def compute_pointcloud_overlaps_scikit(pointcloud1, pointcloud2, distance_threshold, compute_symmetric=False):
|
||||
"""
|
||||
Compute 'overlapping' metrics based on a distance threshold between two point clouds.
|
||||
"""
|
||||
nbrs = NearestNeighbors(n_neighbors=1, algorithm = 'kd_tree').fit(pointcloud2)
|
||||
distances, indices = nbrs.kneighbors(pointcloud1)
|
||||
intersection1 = np.count_nonzero(distances.flatten() < distance_threshold)
|
||||
|
||||
data = {"intersection1": intersection1,
|
||||
"size1": len(pointcloud1)}
|
||||
if compute_symmetric:
|
||||
nbrs = NearestNeighbors(n_neighbors=1, algorithm = 'kd_tree').fit(pointcloud1)
|
||||
distances, indices = nbrs.kneighbors(pointcloud2)
|
||||
intersection2 = np.count_nonzero(distances.flatten() < distance_threshold)
|
||||
data["intersection2"] = intersection2
|
||||
data["size2"] = len(pointcloud2)
|
||||
|
||||
return data
|
||||
|
||||
def _append_camera_parameters(observation, hfov, camera_location, camera_rotation):
|
||||
"""
|
||||
Add camera parameters to the observation dictionnary produced by Habitat-Sim
|
||||
In-place modifications.
|
||||
"""
|
||||
R_cam2world, t_cam2world = compute_camera_pose_opencv_convention(camera_location, camera_rotation)
|
||||
height, width = observation['depth'].shape
|
||||
f, cu, cv = compute_camera_intrinsics(height, width, hfov)
|
||||
K = np.asarray([[f, 0, cu],
|
||||
[0, f, cv],
|
||||
[0, 0, 1.0]])
|
||||
observation["camera_intrinsics"] = K
|
||||
observation["t_cam2world"] = t_cam2world
|
||||
observation["R_cam2world"] = R_cam2world
|
||||
|
||||
def look_at(eye, center, up, return_cam2world=True):
|
||||
"""
|
||||
Return camera pose looking at a given center point.
|
||||
Analogous of gluLookAt function, using OpenCV camera convention.
|
||||
"""
|
||||
z = center - eye
|
||||
z /= np.linalg.norm(z, axis=-1, keepdims=True)
|
||||
y = -up
|
||||
y = y - np.sum(y * z, axis=-1, keepdims=True) * z
|
||||
y /= np.linalg.norm(y, axis=-1, keepdims=True)
|
||||
x = np.cross(y, z, axis=-1)
|
||||
|
||||
if return_cam2world:
|
||||
R = np.stack((x, y, z), axis=-1)
|
||||
t = eye
|
||||
else:
|
||||
# World to camera transformation
|
||||
# Transposed matrix
|
||||
R = np.stack((x, y, z), axis=-2)
|
||||
t = - np.einsum('...ij, ...j', R, eye)
|
||||
return R, t
|
||||
|
||||
def look_at_for_habitat(eye, center, up, return_cam2world=True):
|
||||
R, t = look_at(eye, center, up)
|
||||
orientation = quaternion.from_rotation_matrix(R @ R_OPENCV2HABITAT.T)
|
||||
return orientation, t
|
||||
|
||||
def generate_orientation_noise(pan_range, tilt_range, roll_range):
|
||||
return (quaternion.from_rotation_vector(np.random.uniform(*pan_range) * DEG2RAD * habitat_sim.geo.UP)
|
||||
* quaternion.from_rotation_vector(np.random.uniform(*tilt_range) * DEG2RAD * habitat_sim.geo.RIGHT)
|
||||
* quaternion.from_rotation_vector(np.random.uniform(*roll_range) * DEG2RAD * habitat_sim.geo.FRONT))
|
||||
|
||||
|
||||
class NoNaviguableSpaceError(RuntimeError):
|
||||
def __init__(self, *args):
|
||||
super().__init__(*args)
|
||||
|
||||
class MultiviewHabitatSimGenerator:
|
||||
def __init__(self,
|
||||
scene,
|
||||
navmesh,
|
||||
scene_dataset_config_file,
|
||||
resolution = (240, 320),
|
||||
views_count=2,
|
||||
hfov = 60,
|
||||
gpu_id = 0,
|
||||
size = 10000,
|
||||
minimum_covisibility = 0.5,
|
||||
transform = None):
|
||||
self.scene = scene
|
||||
self.navmesh = navmesh
|
||||
self.scene_dataset_config_file = scene_dataset_config_file
|
||||
self.resolution = resolution
|
||||
self.views_count = views_count
|
||||
assert(self.views_count >= 1)
|
||||
self.hfov = hfov
|
||||
self.gpu_id = gpu_id
|
||||
self.size = size
|
||||
self.transform = transform
|
||||
|
||||
# Noise added to camera orientation
|
||||
self.pan_range = (-3, 3)
|
||||
self.tilt_range = (-10, 10)
|
||||
self.roll_range = (-5, 5)
|
||||
|
||||
# Height range to sample cameras
|
||||
self.height_range = (1.2, 1.8)
|
||||
|
||||
# Random steps between the camera views
|
||||
self.random_steps_count = 5
|
||||
self.random_step_variance = 2.0
|
||||
|
||||
# Minimum fraction of the scene which should be valid (well defined depth)
|
||||
self.minimum_valid_fraction = 0.7
|
||||
|
||||
# Distance threshold to see to select pairs
|
||||
self.distance_threshold = 0.05
|
||||
# Minimum IoU of a view point cloud with respect to the reference view to be kept.
|
||||
self.minimum_covisibility = minimum_covisibility
|
||||
|
||||
# Maximum number of retries.
|
||||
self.max_attempts_count = 100
|
||||
|
||||
self.seed = None
|
||||
self._lazy_initialization()
|
||||
|
||||
def _lazy_initialization(self):
|
||||
# Lazy random seeding and instantiation of the simulator to deal with multiprocessing properly
|
||||
if self.seed == None:
|
||||
# Re-seed numpy generator
|
||||
np.random.seed()
|
||||
self.seed = np.random.randint(2**32-1)
|
||||
sim_cfg = habitat_sim.SimulatorConfiguration()
|
||||
sim_cfg.scene_id = self.scene
|
||||
if self.scene_dataset_config_file is not None and self.scene_dataset_config_file != "":
|
||||
sim_cfg.scene_dataset_config_file = self.scene_dataset_config_file
|
||||
sim_cfg.random_seed = self.seed
|
||||
sim_cfg.load_semantic_mesh = False
|
||||
sim_cfg.gpu_device_id = self.gpu_id
|
||||
|
||||
depth_sensor_spec = habitat_sim.CameraSensorSpec()
|
||||
depth_sensor_spec.uuid = "depth"
|
||||
depth_sensor_spec.sensor_type = habitat_sim.SensorType.DEPTH
|
||||
depth_sensor_spec.resolution = self.resolution
|
||||
depth_sensor_spec.hfov = self.hfov
|
||||
depth_sensor_spec.position = [0.0, 0.0, 0]
|
||||
depth_sensor_spec.orientation
|
||||
|
||||
rgb_sensor_spec = habitat_sim.CameraSensorSpec()
|
||||
rgb_sensor_spec.uuid = "color"
|
||||
rgb_sensor_spec.sensor_type = habitat_sim.SensorType.COLOR
|
||||
rgb_sensor_spec.resolution = self.resolution
|
||||
rgb_sensor_spec.hfov = self.hfov
|
||||
rgb_sensor_spec.position = [0.0, 0.0, 0]
|
||||
agent_cfg = habitat_sim.agent.AgentConfiguration(sensor_specifications=[rgb_sensor_spec, depth_sensor_spec])
|
||||
|
||||
cfg = habitat_sim.Configuration(sim_cfg, [agent_cfg])
|
||||
self.sim = habitat_sim.Simulator(cfg)
|
||||
if self.navmesh is not None and self.navmesh != "":
|
||||
# Use pre-computed navmesh when available (usually better than those generated automatically)
|
||||
self.sim.pathfinder.load_nav_mesh(self.navmesh)
|
||||
|
||||
if not self.sim.pathfinder.is_loaded:
|
||||
# Try to compute a navmesh
|
||||
navmesh_settings = habitat_sim.NavMeshSettings()
|
||||
navmesh_settings.set_defaults()
|
||||
self.sim.recompute_navmesh(self.sim.pathfinder, navmesh_settings, True)
|
||||
|
||||
# Ensure that the navmesh is not empty
|
||||
if not self.sim.pathfinder.is_loaded:
|
||||
raise NoNaviguableSpaceError(f"No naviguable location (scene: {self.scene} -- navmesh: {self.navmesh})")
|
||||
|
||||
self.agent = self.sim.initialize_agent(agent_id=0)
|
||||
|
||||
def close(self):
|
||||
self.sim.close()
|
||||
|
||||
def __del__(self):
|
||||
self.sim.close()
|
||||
|
||||
def __len__(self):
|
||||
return self.size
|
||||
|
||||
def sample_random_viewpoint(self):
|
||||
""" Sample a random viewpoint using the navmesh """
|
||||
nav_point = self.sim.pathfinder.get_random_navigable_point()
|
||||
|
||||
# Sample a random viewpoint height
|
||||
viewpoint_height = np.random.uniform(*self.height_range)
|
||||
viewpoint_position = nav_point + viewpoint_height * habitat_sim.geo.UP
|
||||
viewpoint_orientation = quaternion.from_rotation_vector(np.random.uniform(0, 2 * np.pi) * habitat_sim.geo.UP) * generate_orientation_noise(self.pan_range, self.tilt_range, self.roll_range)
|
||||
return viewpoint_position, viewpoint_orientation, nav_point
|
||||
|
||||
def sample_other_random_viewpoint(self, observed_point, nav_point):
|
||||
""" Sample a random viewpoint close to an existing one, using the navmesh and a reference observed point."""
|
||||
other_nav_point = nav_point
|
||||
|
||||
walk_directions = self.random_step_variance * np.asarray([1,0,1])
|
||||
for i in range(self.random_steps_count):
|
||||
temp = self.sim.pathfinder.snap_point(other_nav_point + walk_directions * np.random.normal(size=3))
|
||||
# Snapping may return nan when it fails
|
||||
if not np.isnan(temp[0]):
|
||||
other_nav_point = temp
|
||||
|
||||
other_viewpoint_height = np.random.uniform(*self.height_range)
|
||||
other_viewpoint_position = other_nav_point + other_viewpoint_height * habitat_sim.geo.UP
|
||||
|
||||
# Set viewing direction towards the central point
|
||||
rotation, position = look_at_for_habitat(eye=other_viewpoint_position, center=observed_point, up=habitat_sim.geo.UP, return_cam2world=True)
|
||||
rotation = rotation * generate_orientation_noise(self.pan_range, self.tilt_range, self.roll_range)
|
||||
return position, rotation, other_nav_point
|
||||
|
||||
def is_other_pointcloud_overlapping(self, ref_pointcloud, other_pointcloud):
|
||||
""" Check if a viewpoint is valid and overlaps significantly with a reference one. """
|
||||
# Observation
|
||||
pixels_count = self.resolution[0] * self.resolution[1]
|
||||
valid_fraction = len(other_pointcloud) / pixels_count
|
||||
assert valid_fraction <= 1.0 and valid_fraction >= 0.0
|
||||
overlap = compute_pointcloud_overlaps_scikit(ref_pointcloud, other_pointcloud, self.distance_threshold, compute_symmetric=True)
|
||||
covisibility = min(overlap["intersection1"] / pixels_count, overlap["intersection2"] / pixels_count)
|
||||
is_valid = (valid_fraction >= self.minimum_valid_fraction) and (covisibility >= self.minimum_covisibility)
|
||||
return is_valid, valid_fraction, covisibility
|
||||
|
||||
def is_other_viewpoint_overlapping(self, ref_pointcloud, observation, position, rotation):
|
||||
""" Check if a viewpoint is valid and overlaps significantly with a reference one. """
|
||||
# Observation
|
||||
other_pointcloud = compute_pointcloud(observation['depth'], self.hfov, position, rotation)
|
||||
return self.is_other_pointcloud_overlapping(ref_pointcloud, other_pointcloud)
|
||||
|
||||
def render_viewpoint(self, viewpoint_position, viewpoint_orientation):
|
||||
agent_state = habitat_sim.AgentState()
|
||||
agent_state.position = viewpoint_position
|
||||
agent_state.rotation = viewpoint_orientation
|
||||
self.agent.set_state(agent_state)
|
||||
viewpoint_observations = self.sim.get_sensor_observations(agent_ids=0)
|
||||
_append_camera_parameters(viewpoint_observations, self.hfov, viewpoint_position, viewpoint_orientation)
|
||||
return viewpoint_observations
|
||||
|
||||
def __getitem__(self, useless_idx):
|
||||
ref_position, ref_orientation, nav_point = self.sample_random_viewpoint()
|
||||
ref_observations = self.render_viewpoint(ref_position, ref_orientation)
|
||||
# Extract point cloud
|
||||
ref_pointcloud = compute_pointcloud(depthmap=ref_observations['depth'], hfov=self.hfov,
|
||||
camera_position=ref_position, camera_rotation=ref_orientation)
|
||||
|
||||
pixels_count = self.resolution[0] * self.resolution[1]
|
||||
ref_valid_fraction = len(ref_pointcloud) / pixels_count
|
||||
assert ref_valid_fraction <= 1.0 and ref_valid_fraction >= 0.0
|
||||
if ref_valid_fraction < self.minimum_valid_fraction:
|
||||
# This should produce a recursion error at some point when something is very wrong.
|
||||
return self[0]
|
||||
# Pick an reference observed point in the point cloud
|
||||
observed_point = np.mean(ref_pointcloud, axis=0)
|
||||
|
||||
# Add the first image as reference
|
||||
viewpoints_observations = [ref_observations]
|
||||
viewpoints_covisibility = [ref_valid_fraction]
|
||||
viewpoints_positions = [ref_position]
|
||||
viewpoints_orientations = [quaternion.as_float_array(ref_orientation)]
|
||||
viewpoints_clouds = [ref_pointcloud]
|
||||
viewpoints_valid_fractions = [ref_valid_fraction]
|
||||
|
||||
for _ in range(self.views_count - 1):
|
||||
# Generate an other viewpoint using some dummy random walk
|
||||
successful_sampling = False
|
||||
for sampling_attempt in range(self.max_attempts_count):
|
||||
position, rotation, _ = self.sample_other_random_viewpoint(observed_point, nav_point)
|
||||
# Observation
|
||||
other_viewpoint_observations = self.render_viewpoint(position, rotation)
|
||||
other_pointcloud = compute_pointcloud(other_viewpoint_observations['depth'], self.hfov, position, rotation)
|
||||
|
||||
is_valid, valid_fraction, covisibility = self.is_other_pointcloud_overlapping(ref_pointcloud, other_pointcloud)
|
||||
if is_valid:
|
||||
successful_sampling = True
|
||||
break
|
||||
if not successful_sampling:
|
||||
print("WARNING: Maximum number of attempts reached.")
|
||||
# Dirty hack, try using a novel original viewpoint
|
||||
return self[0]
|
||||
viewpoints_observations.append(other_viewpoint_observations)
|
||||
viewpoints_covisibility.append(covisibility)
|
||||
viewpoints_positions.append(position)
|
||||
viewpoints_orientations.append(quaternion.as_float_array(rotation)) # WXYZ convention for the quaternion encoding.
|
||||
viewpoints_clouds.append(other_pointcloud)
|
||||
viewpoints_valid_fractions.append(valid_fraction)
|
||||
|
||||
# Estimate relations between all pairs of images
|
||||
pairwise_visibility_ratios = np.ones((len(viewpoints_observations), len(viewpoints_observations)))
|
||||
for i in range(len(viewpoints_observations)):
|
||||
pairwise_visibility_ratios[i,i] = viewpoints_valid_fractions[i]
|
||||
for j in range(i+1, len(viewpoints_observations)):
|
||||
overlap = compute_pointcloud_overlaps_scikit(viewpoints_clouds[i], viewpoints_clouds[j], self.distance_threshold, compute_symmetric=True)
|
||||
pairwise_visibility_ratios[i,j] = overlap['intersection1'] / pixels_count
|
||||
pairwise_visibility_ratios[j,i] = overlap['intersection2'] / pixels_count
|
||||
|
||||
# IoU is relative to the image 0
|
||||
data = {"observations": viewpoints_observations,
|
||||
"positions": np.asarray(viewpoints_positions),
|
||||
"orientations": np.asarray(viewpoints_orientations),
|
||||
"covisibility_ratios": np.asarray(viewpoints_covisibility),
|
||||
"valid_fractions": np.asarray(viewpoints_valid_fractions, dtype=float),
|
||||
"pairwise_visibility_ratios": np.asarray(pairwise_visibility_ratios, dtype=float),
|
||||
}
|
||||
|
||||
if self.transform is not None:
|
||||
data = self.transform(data)
|
||||
return data
|
||||
|
||||
def generate_random_spiral_trajectory(self, images_count = 100, max_radius=0.5, half_turns=5, use_constant_orientation=False):
|
||||
"""
|
||||
Return a list of images corresponding to a spiral trajectory from a random starting point.
|
||||
Useful to generate nice visualisations.
|
||||
Use an even number of half turns to get a nice "C1-continuous" loop effect
|
||||
"""
|
||||
ref_position, ref_orientation, navpoint = self.sample_random_viewpoint()
|
||||
ref_observations = self.render_viewpoint(ref_position, ref_orientation)
|
||||
ref_pointcloud = compute_pointcloud(depthmap=ref_observations['depth'], hfov=self.hfov,
|
||||
camera_position=ref_position, camera_rotation=ref_orientation)
|
||||
pixels_count = self.resolution[0] * self.resolution[1]
|
||||
if len(ref_pointcloud) / pixels_count < self.minimum_valid_fraction:
|
||||
# Dirty hack: ensure that the valid part of the image is significant
|
||||
return self.generate_random_spiral_trajectory(images_count, max_radius, half_turns, use_constant_orientation)
|
||||
|
||||
# Pick an observed point in the point cloud
|
||||
observed_point = np.mean(ref_pointcloud, axis=0)
|
||||
ref_R, ref_t = compute_camera_pose_opencv_convention(ref_position, ref_orientation)
|
||||
|
||||
images = []
|
||||
is_valid = []
|
||||
# Spiral trajectory, use_constant orientation
|
||||
for i, alpha in enumerate(np.linspace(0, 1, images_count)):
|
||||
r = max_radius * np.abs(np.sin(alpha * np.pi)) # Increase then decrease the radius
|
||||
theta = alpha * half_turns * np.pi
|
||||
x = r * np.cos(theta)
|
||||
y = r * np.sin(theta)
|
||||
z = 0.0
|
||||
position = ref_position + (ref_R @ np.asarray([x, y, z]).reshape(3,1)).flatten()
|
||||
if use_constant_orientation:
|
||||
orientation = ref_orientation
|
||||
else:
|
||||
# trajectory looking at a mean point in front of the ref observation
|
||||
orientation, position = look_at_for_habitat(eye=position, center=observed_point, up=habitat_sim.geo.UP)
|
||||
observations = self.render_viewpoint(position, orientation)
|
||||
images.append(observations['color'][...,:3])
|
||||
_is_valid, valid_fraction, iou = self.is_other_viewpoint_overlapping(ref_pointcloud, observations, position, orientation)
|
||||
is_valid.append(_is_valid)
|
||||
return images, np.all(is_valid)
|
||||
@@ -0,0 +1,69 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
"""
|
||||
Utility script to pack metadata files of the dataset in order to be able to re-generate it elsewhere.
|
||||
"""
|
||||
import os
|
||||
import glob
|
||||
from tqdm import tqdm
|
||||
import shutil
|
||||
import json
|
||||
from datasets.habitat_sim.paths import *
|
||||
import argparse
|
||||
import collections
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("input_dir")
|
||||
parser.add_argument("output_dir")
|
||||
args = parser.parse_args()
|
||||
|
||||
input_dirname = args.input_dir
|
||||
output_dirname = args.output_dir
|
||||
|
||||
input_metadata_filenames = glob.iglob(f"{input_dirname}/**/metadata.json", recursive=True)
|
||||
|
||||
images_count = collections.defaultdict(lambda : 0)
|
||||
|
||||
os.makedirs(output_dirname)
|
||||
for input_filename in tqdm(input_metadata_filenames):
|
||||
# Ignore empty files
|
||||
with open(input_filename, "r") as f:
|
||||
original_metadata = json.load(f)
|
||||
if "multiviews" not in original_metadata or len(original_metadata["multiviews"]) == 0:
|
||||
print("No views in", input_filename)
|
||||
continue
|
||||
|
||||
relpath = os.path.relpath(input_filename, input_dirname)
|
||||
print(relpath)
|
||||
|
||||
# Copy metadata, while replacing scene paths by generic keys depending on the dataset, for portability.
|
||||
# Data paths are sorted by decreasing length to avoid potential bugs due to paths starting by the same string pattern.
|
||||
scenes_dataset_paths = dict(sorted(SCENES_DATASET.items(), key=lambda x: len(x[1]), reverse=True))
|
||||
metadata = dict()
|
||||
for key, value in original_metadata.items():
|
||||
if key in ("scene_dataset_config_file", "scene", "navmesh") and value != "":
|
||||
known_path = False
|
||||
for dataset, dataset_path in scenes_dataset_paths.items():
|
||||
if value.startswith(dataset_path):
|
||||
value = os.path.join(dataset, os.path.relpath(value, dataset_path))
|
||||
known_path = True
|
||||
break
|
||||
if not known_path:
|
||||
raise KeyError("Unknown path:" + value)
|
||||
metadata[key] = value
|
||||
|
||||
# Compile some general statistics while packing data
|
||||
scene_split = metadata["scene"].split("/")
|
||||
upper_level = "/".join(scene_split[:2]) if scene_split[0] == "hm3d" else scene_split[0]
|
||||
images_count[upper_level] += len(metadata["multiviews"])
|
||||
|
||||
output_filename = os.path.join(output_dirname, relpath)
|
||||
os.makedirs(os.path.dirname(output_filename), exist_ok=True)
|
||||
with open(output_filename, "w") as f:
|
||||
json.dump(metadata, f)
|
||||
|
||||
# Print statistics
|
||||
print("Images count:")
|
||||
for upper_level, count in images_count.items():
|
||||
print(f"- {upper_level}: {count}")
|
||||
@@ -0,0 +1,129 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
"""
|
||||
Paths to Habitat-Sim scenes
|
||||
"""
|
||||
|
||||
import os
|
||||
import json
|
||||
import collections
|
||||
from tqdm import tqdm
|
||||
|
||||
|
||||
# Hardcoded path to the different scene datasets
|
||||
SCENES_DATASET = {
|
||||
"hm3d": "./data/habitat-sim-data/scene_datasets/hm3d/",
|
||||
"gibson": "./data/habitat-sim-data/scene_datasets/gibson/",
|
||||
"habitat-test-scenes": "./data/habitat-sim/scene_datasets/habitat-test-scenes/",
|
||||
"replica_cad_baked_lighting": "./data/habitat-sim/scene_datasets/replica_cad_baked_lighting/",
|
||||
"replica_cad": "./data/habitat-sim/scene_datasets/replica_cad/",
|
||||
"replica": "./data/habitat-sim/scene_datasets/ReplicaDataset/",
|
||||
"scannet": "./data/habitat-sim/scene_datasets/scannet/"
|
||||
}
|
||||
|
||||
SceneData = collections.namedtuple("SceneData", ["scene_dataset_config_file", "scene", "navmesh", "output_dir"])
|
||||
|
||||
def list_replicacad_scenes(base_output_dir, base_path=SCENES_DATASET["replica_cad"]):
|
||||
scene_dataset_config_file = os.path.join(base_path, "replicaCAD.scene_dataset_config.json")
|
||||
scenes = [f"apt_{i}" for i in range(6)] + ["empty_stage"]
|
||||
navmeshes = [f"navmeshes/apt_{i}_static_furniture.navmesh" for i in range(6)] + ["empty_stage.navmesh"]
|
||||
scenes_data = []
|
||||
for idx in range(len(scenes)):
|
||||
output_dir = os.path.join(base_output_dir, "ReplicaCAD", scenes[idx])
|
||||
# Add scene
|
||||
data = SceneData(scene_dataset_config_file=scene_dataset_config_file,
|
||||
scene = scenes[idx] + ".scene_instance.json",
|
||||
navmesh = os.path.join(base_path, navmeshes[idx]),
|
||||
output_dir = output_dir)
|
||||
scenes_data.append(data)
|
||||
return scenes_data
|
||||
|
||||
def list_replica_cad_baked_lighting_scenes(base_output_dir, base_path=SCENES_DATASET["replica_cad_baked_lighting"]):
|
||||
scene_dataset_config_file = os.path.join(base_path, "replicaCAD_baked.scene_dataset_config.json")
|
||||
scenes = sum([[f"Baked_sc{i}_staging_{j:02}" for i in range(5)] for j in range(21)], [])
|
||||
navmeshes = ""#[f"navmeshes/apt_{i}_static_furniture.navmesh" for i in range(6)] + ["empty_stage.navmesh"]
|
||||
scenes_data = []
|
||||
for idx in range(len(scenes)):
|
||||
output_dir = os.path.join(base_output_dir, "replica_cad_baked_lighting", scenes[idx])
|
||||
data = SceneData(scene_dataset_config_file=scene_dataset_config_file,
|
||||
scene = scenes[idx],
|
||||
navmesh = "",
|
||||
output_dir = output_dir)
|
||||
scenes_data.append(data)
|
||||
return scenes_data
|
||||
|
||||
def list_replica_scenes(base_output_dir, base_path):
|
||||
scenes_data = []
|
||||
for scene_id in os.listdir(base_path):
|
||||
scene = os.path.join(base_path, scene_id, "mesh.ply")
|
||||
navmesh = os.path.join(base_path, scene_id, "habitat/mesh_preseg_semantic.navmesh") # Not sure if I should use it
|
||||
scene_dataset_config_file = ""
|
||||
output_dir = os.path.join(base_output_dir, scene_id)
|
||||
# Add scene only if it does not exist already, or if exist_ok
|
||||
data = SceneData(scene_dataset_config_file = scene_dataset_config_file,
|
||||
scene = scene,
|
||||
navmesh = navmesh,
|
||||
output_dir = output_dir)
|
||||
scenes_data.append(data)
|
||||
return scenes_data
|
||||
|
||||
|
||||
def list_scenes(base_output_dir, base_path):
|
||||
"""
|
||||
Generic method iterating through a base_path folder to find scenes.
|
||||
"""
|
||||
scenes_data = []
|
||||
for root, dirs, files in os.walk(base_path, followlinks=True):
|
||||
folder_scenes_data = []
|
||||
for file in files:
|
||||
name, ext = os.path.splitext(file)
|
||||
if ext == ".glb":
|
||||
scene = os.path.join(root, name + ".glb")
|
||||
navmesh = os.path.join(root, name + ".navmesh")
|
||||
if not os.path.exists(navmesh):
|
||||
navmesh = ""
|
||||
relpath = os.path.relpath(root, base_path)
|
||||
output_dir = os.path.abspath(os.path.join(base_output_dir, relpath, name))
|
||||
data = SceneData(scene_dataset_config_file="",
|
||||
scene = scene,
|
||||
navmesh = navmesh,
|
||||
output_dir = output_dir)
|
||||
folder_scenes_data.append(data)
|
||||
|
||||
# Specific check for HM3D:
|
||||
# When two meshesxxxx.basis.glb and xxxx.glb are present, use the 'basis' version.
|
||||
basis_scenes = [data.scene[:-len(".basis.glb")] for data in folder_scenes_data if data.scene.endswith(".basis.glb")]
|
||||
if len(basis_scenes) != 0:
|
||||
folder_scenes_data = [data for data in folder_scenes_data if not (data.scene[:-len(".glb")] in basis_scenes)]
|
||||
|
||||
scenes_data.extend(folder_scenes_data)
|
||||
return scenes_data
|
||||
|
||||
def list_scenes_available(base_output_dir, scenes_dataset_paths=SCENES_DATASET):
|
||||
scenes_data = []
|
||||
|
||||
# HM3D
|
||||
for split in ("minival", "train", "val", "examples"):
|
||||
scenes_data += list_scenes(base_output_dir=os.path.join(base_output_dir, f"hm3d/{split}/"),
|
||||
base_path=f"{scenes_dataset_paths['hm3d']}/{split}")
|
||||
|
||||
# Gibson
|
||||
scenes_data += list_scenes(base_output_dir=os.path.join(base_output_dir, "gibson"),
|
||||
base_path=scenes_dataset_paths["gibson"])
|
||||
|
||||
# Habitat test scenes (just a few)
|
||||
scenes_data += list_scenes(base_output_dir=os.path.join(base_output_dir, "habitat-test-scenes"),
|
||||
base_path=scenes_dataset_paths["habitat-test-scenes"])
|
||||
|
||||
# ReplicaCAD (baked lightning)
|
||||
scenes_data += list_replica_cad_baked_lighting_scenes(base_output_dir=base_output_dir)
|
||||
|
||||
# ScanNet
|
||||
scenes_data += list_scenes(base_output_dir=os.path.join(base_output_dir, "scannet"),
|
||||
base_path=scenes_dataset_paths["scannet"])
|
||||
|
||||
# Replica
|
||||
list_replica_scenes(base_output_dir=os.path.join(base_output_dir, "replica"),
|
||||
base_path=scenes_dataset_paths["replica"])
|
||||
return scenes_data
|
||||
@@ -0,0 +1,109 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
import os
|
||||
from torch.utils.data import Dataset
|
||||
from PIL import Image
|
||||
|
||||
from datasets.transforms import get_pair_transforms
|
||||
|
||||
def load_image(impath):
|
||||
return Image.open(impath)
|
||||
|
||||
def load_pairs_from_cache_file(fname, root=''):
|
||||
assert os.path.isfile(fname), "cannot parse pairs from {:s}, file does not exist".format(fname)
|
||||
with open(fname, 'r') as fid:
|
||||
lines = fid.read().strip().splitlines()
|
||||
pairs = [ (os.path.join(root,l.split()[0]), os.path.join(root,l.split()[1])) for l in lines]
|
||||
return pairs
|
||||
|
||||
def load_pairs_from_list_file(fname, root=''):
|
||||
assert os.path.isfile(fname), "cannot parse pairs from {:s}, file does not exist".format(fname)
|
||||
with open(fname, 'r') as fid:
|
||||
lines = fid.read().strip().splitlines()
|
||||
pairs = [ (os.path.join(root,l+'_1.jpg'), os.path.join(root,l+'_2.jpg')) for l in lines if not l.startswith('#')]
|
||||
return pairs
|
||||
|
||||
|
||||
def write_cache_file(fname, pairs, root=''):
|
||||
if len(root)>0:
|
||||
if not root.endswith('/'): root+='/'
|
||||
assert os.path.isdir(root)
|
||||
s = ''
|
||||
for im1, im2 in pairs:
|
||||
if len(root)>0:
|
||||
assert im1.startswith(root), im1
|
||||
assert im2.startswith(root), im2
|
||||
s += '{:s} {:s}\n'.format(im1[len(root):], im2[len(root):])
|
||||
with open(fname, 'w') as fid:
|
||||
fid.write(s[:-1])
|
||||
|
||||
def parse_and_cache_all_pairs(dname, data_dir='./data/'):
|
||||
if dname=='habitat_release':
|
||||
dirname = os.path.join(data_dir, 'habitat_release')
|
||||
assert os.path.isdir(dirname), "cannot find folder for habitat_release pairs: "+dirname
|
||||
cache_file = os.path.join(dirname, 'pairs.txt')
|
||||
assert not os.path.isfile(cache_file), "cache file already exists: "+cache_file
|
||||
|
||||
print('Parsing pairs for dataset: '+dname)
|
||||
pairs = []
|
||||
for root, dirs, files in os.walk(dirname):
|
||||
if 'val' in root: continue
|
||||
dirs.sort()
|
||||
pairs += [ (os.path.join(root,f), os.path.join(root,f[:-len('_1.jpeg')]+'_2.jpeg')) for f in sorted(files) if f.endswith('_1.jpeg')]
|
||||
print('Found {:,} pairs'.format(len(pairs)))
|
||||
print('Writing cache to: '+cache_file)
|
||||
write_cache_file(cache_file, pairs, root=dirname)
|
||||
|
||||
else:
|
||||
raise NotImplementedError('Unknown dataset: '+dname)
|
||||
|
||||
def dnames_to_image_pairs(dnames, data_dir='./data/'):
|
||||
"""
|
||||
dnames: list of datasets with image pairs, separated by +
|
||||
"""
|
||||
all_pairs = []
|
||||
for dname in dnames.split('+'):
|
||||
if dname=='habitat_release':
|
||||
dirname = os.path.join(data_dir, 'habitat_release')
|
||||
assert os.path.isdir(dirname), "cannot find folder for habitat_release pairs: "+dirname
|
||||
cache_file = os.path.join(dirname, 'pairs.txt')
|
||||
assert os.path.isfile(cache_file), "cannot find cache file for habitat_release pairs, please first create the cache file, see instructions. "+cache_file
|
||||
pairs = load_pairs_from_cache_file(cache_file, root=dirname)
|
||||
elif dname in ['ARKitScenes', 'MegaDepth', '3DStreetView', 'IndoorVL']:
|
||||
dirname = os.path.join(data_dir, dname+'_crops')
|
||||
assert os.path.isdir(dirname), "cannot find folder for {:s} pairs: {:s}".format(dname, dirname)
|
||||
list_file = os.path.join(dirname, 'listing.txt')
|
||||
assert os.path.isfile(list_file), "cannot find list file for {:s} pairs, see instructions. {:s}".format(dname, list_file)
|
||||
pairs = load_pairs_from_list_file(list_file, root=dirname)
|
||||
print(' {:s}: {:,} pairs'.format(dname, len(pairs)))
|
||||
all_pairs += pairs
|
||||
if '+' in dnames: print(' Total: {:,} pairs'.format(len(all_pairs)))
|
||||
return all_pairs
|
||||
|
||||
|
||||
class PairsDataset(Dataset):
|
||||
|
||||
def __init__(self, dnames, trfs='', totensor=True, normalize=True, data_dir='./data/'):
|
||||
super().__init__()
|
||||
self.image_pairs = dnames_to_image_pairs(dnames, data_dir=data_dir)
|
||||
self.transforms = get_pair_transforms(transform_str=trfs, totensor=totensor, normalize=normalize)
|
||||
|
||||
def __len__(self):
|
||||
return len(self.image_pairs)
|
||||
|
||||
def __getitem__(self, index):
|
||||
im1path, im2path = self.image_pairs[index]
|
||||
im1 = load_image(im1path)
|
||||
im2 = load_image(im2path)
|
||||
if self.transforms is not None: im1, im2 = self.transforms(im1, im2)
|
||||
return im1, im2
|
||||
|
||||
|
||||
if __name__=="__main__":
|
||||
import argparse
|
||||
parser = argparse.ArgumentParser(prog="Computing and caching list of pairs for a given dataset")
|
||||
parser.add_argument('--data_dir', default='./data/', type=str, help="path where data are stored")
|
||||
parser.add_argument('--dataset', default='habitat_release', type=str, help="name of the dataset")
|
||||
args = parser.parse_args()
|
||||
parse_and_cache_all_pairs(dname=args.dataset, data_dir=args.data_dir)
|
||||
@@ -0,0 +1,95 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
import torch
|
||||
import torchvision.transforms
|
||||
import torchvision.transforms.functional as F
|
||||
|
||||
# "Pair": apply a transform on a pair
|
||||
# "Both": apply the exact same transform to both images
|
||||
|
||||
class ComposePair(torchvision.transforms.Compose):
|
||||
def __call__(self, img1, img2):
|
||||
for t in self.transforms:
|
||||
img1, img2 = t(img1, img2)
|
||||
return img1, img2
|
||||
|
||||
class NormalizeBoth(torchvision.transforms.Normalize):
|
||||
def forward(self, img1, img2):
|
||||
img1 = super().forward(img1)
|
||||
img2 = super().forward(img2)
|
||||
return img1, img2
|
||||
|
||||
class ToTensorBoth(torchvision.transforms.ToTensor):
|
||||
def __call__(self, img1, img2):
|
||||
img1 = super().__call__(img1)
|
||||
img2 = super().__call__(img2)
|
||||
return img1, img2
|
||||
|
||||
class RandomCropPair(torchvision.transforms.RandomCrop):
|
||||
# the crop will be intentionally different for the two images with this class
|
||||
def forward(self, img1, img2):
|
||||
img1 = super().forward(img1)
|
||||
img2 = super().forward(img2)
|
||||
return img1, img2
|
||||
|
||||
class ColorJitterPair(torchvision.transforms.ColorJitter):
|
||||
# can be symmetric (same for both images) or assymetric (different jitter params for each image) depending on assymetric_prob
|
||||
def __init__(self, assymetric_prob, **kwargs):
|
||||
super().__init__(**kwargs)
|
||||
self.assymetric_prob = assymetric_prob
|
||||
def jitter_one(self, img, fn_idx, brightness_factor, contrast_factor, saturation_factor, hue_factor):
|
||||
for fn_id in fn_idx:
|
||||
if fn_id == 0 and brightness_factor is not None:
|
||||
img = F.adjust_brightness(img, brightness_factor)
|
||||
elif fn_id == 1 and contrast_factor is not None:
|
||||
img = F.adjust_contrast(img, contrast_factor)
|
||||
elif fn_id == 2 and saturation_factor is not None:
|
||||
img = F.adjust_saturation(img, saturation_factor)
|
||||
elif fn_id == 3 and hue_factor is not None:
|
||||
img = F.adjust_hue(img, hue_factor)
|
||||
return img
|
||||
|
||||
def forward(self, img1, img2):
|
||||
|
||||
fn_idx, brightness_factor, contrast_factor, saturation_factor, hue_factor = self.get_params(
|
||||
self.brightness, self.contrast, self.saturation, self.hue
|
||||
)
|
||||
img1 = self.jitter_one(img1, fn_idx, brightness_factor, contrast_factor, saturation_factor, hue_factor)
|
||||
if torch.rand(1) < self.assymetric_prob: # assymetric:
|
||||
fn_idx, brightness_factor, contrast_factor, saturation_factor, hue_factor = self.get_params(
|
||||
self.brightness, self.contrast, self.saturation, self.hue
|
||||
)
|
||||
img2 = self.jitter_one(img2, fn_idx, brightness_factor, contrast_factor, saturation_factor, hue_factor)
|
||||
return img1, img2
|
||||
|
||||
def get_pair_transforms(transform_str, totensor=True, normalize=True):
|
||||
# transform_str is eg crop224+color
|
||||
trfs = []
|
||||
for s in transform_str.split('+'):
|
||||
if s.startswith('crop'):
|
||||
size = int(s[len('crop'):])
|
||||
trfs.append(RandomCropPair(size))
|
||||
elif s=='acolor':
|
||||
trfs.append(ColorJitterPair(assymetric_prob=1.0, brightness=(0.6, 1.4), contrast=(0.6, 1.4), saturation=(0.6, 1.4), hue=0.0))
|
||||
elif s=='': # if transform_str was ""
|
||||
pass
|
||||
else:
|
||||
raise NotImplementedError('Unknown augmentation: '+s)
|
||||
|
||||
if totensor:
|
||||
trfs.append( ToTensorBoth() )
|
||||
if normalize:
|
||||
trfs.append( NormalizeBoth(mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225]) )
|
||||
|
||||
if len(trfs)==0:
|
||||
return None
|
||||
elif len(trfs)==1:
|
||||
return trfs
|
||||
else:
|
||||
return ComposePair(trfs)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
+55
@@ -0,0 +1,55 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
import torch
|
||||
from models.croco import CroCoNet
|
||||
from PIL import Image
|
||||
import torchvision.transforms
|
||||
from torchvision.transforms import ToTensor, Normalize, Compose
|
||||
|
||||
def main():
|
||||
device = torch.device('cuda:0' if torch.cuda.is_available() and torch.cuda.device_count()>0 else 'cpu')
|
||||
|
||||
# load 224x224 images and transform them to tensor
|
||||
imagenet_mean = [0.485, 0.456, 0.406]
|
||||
imagenet_mean_tensor = torch.tensor(imagenet_mean).view(1,3,1,1).to(device, non_blocking=True)
|
||||
imagenet_std = [0.229, 0.224, 0.225]
|
||||
imagenet_std_tensor = torch.tensor(imagenet_std).view(1,3,1,1).to(device, non_blocking=True)
|
||||
trfs = Compose([ToTensor(), Normalize(mean=imagenet_mean, std=imagenet_std)])
|
||||
image1 = trfs(Image.open('assets/Chateau1.png').convert('RGB')).to(device, non_blocking=True).unsqueeze(0)
|
||||
image2 = trfs(Image.open('assets/Chateau2.png').convert('RGB')).to(device, non_blocking=True).unsqueeze(0)
|
||||
|
||||
# load model
|
||||
ckpt = torch.load('pretrained_models/CroCo_V2_ViTLarge_BaseDecoder.pth', 'cpu')
|
||||
model = CroCoNet( **ckpt.get('croco_kwargs',{})).to(device)
|
||||
model.eval()
|
||||
msg = model.load_state_dict(ckpt['model'], strict=True)
|
||||
|
||||
# forward
|
||||
with torch.inference_mode():
|
||||
out, mask, target = model(image1, image2)
|
||||
|
||||
# the output is normalized, thus use the mean/std of the actual image to go back to RGB space
|
||||
patchified = model.patchify(image1)
|
||||
mean = patchified.mean(dim=-1, keepdim=True)
|
||||
var = patchified.var(dim=-1, keepdim=True)
|
||||
decoded_image = model.unpatchify(out * (var + 1.e-6)**.5 + mean)
|
||||
# undo imagenet normalization, prepare masked image
|
||||
decoded_image = decoded_image * imagenet_std_tensor + imagenet_mean_tensor
|
||||
input_image = image1 * imagenet_std_tensor + imagenet_mean_tensor
|
||||
ref_image = image2 * imagenet_std_tensor + imagenet_mean_tensor
|
||||
image_masks = model.unpatchify(model.patchify(torch.ones_like(ref_image)) * mask[:,:,None])
|
||||
masked_input_image = ((1 - image_masks) * input_image)
|
||||
|
||||
# make visualization
|
||||
visualization = torch.cat((ref_image, masked_input_image, decoded_image, input_image), dim=3) # 4*(B, 3, H, W) -> B, 3, H, W*4
|
||||
B, C, H, W = visualization.shape
|
||||
visualization = visualization.permute(1, 0, 2, 3).reshape(C, B*H, W)
|
||||
visualization = torchvision.transforms.functional.to_pil_image(torch.clamp(visualization, 0, 1))
|
||||
fname = "demo_output.png"
|
||||
visualization.save(fname)
|
||||
print('Visualization save in '+fname)
|
||||
|
||||
|
||||
if __name__=="__main__":
|
||||
main()
|
||||
@@ -0,0 +1,271 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"# Interactive demo of Cross-view Completion."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Copyright (C) 2022-present Naver Corporation. All rights reserved.\n",
|
||||
"# Licensed under CC BY-NC-SA 4.0 (non-commercial use only)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import torch\n",
|
||||
"import numpy as np\n",
|
||||
"from models.croco import CroCoNet\n",
|
||||
"from ipywidgets import interact, interactive, fixed, interact_manual\n",
|
||||
"import ipywidgets as widgets\n",
|
||||
"import matplotlib.pyplot as plt\n",
|
||||
"import quaternion\n",
|
||||
"import models.masking"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"### Load CroCo model"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"ckpt = torch.load('pretrained_models/CroCo_V2_ViTLarge_BaseDecoder.pth', 'cpu')\n",
|
||||
"model = CroCoNet( **ckpt.get('croco_kwargs',{}))\n",
|
||||
"msg = model.load_state_dict(ckpt['model'], strict=True)\n",
|
||||
"use_gpu = torch.cuda.is_available() and torch.cuda.device_count()>0\n",
|
||||
"device = torch.device('cuda:0' if use_gpu else 'cpu')\n",
|
||||
"model = model.eval()\n",
|
||||
"model = model.to(device=device)\n",
|
||||
"print(msg)\n",
|
||||
"\n",
|
||||
"def process_images(ref_image, target_image, masking_ratio, reconstruct_unmasked_patches=False):\n",
|
||||
" \"\"\"\n",
|
||||
" Perform Cross-View completion using two input images, specified using Numpy arrays.\n",
|
||||
" \"\"\"\n",
|
||||
" # Replace the mask generator\n",
|
||||
" model.mask_generator = models.masking.RandomMask(model.patch_embed.num_patches, masking_ratio)\n",
|
||||
"\n",
|
||||
" # ImageNet-1k color normalization\n",
|
||||
" imagenet_mean = torch.as_tensor([0.485, 0.456, 0.406]).reshape(1,3,1,1).to(device)\n",
|
||||
" imagenet_std = torch.as_tensor([0.229, 0.224, 0.225]).reshape(1,3,1,1).to(device)\n",
|
||||
"\n",
|
||||
" normalize_input_colors = True\n",
|
||||
" is_output_normalized = True\n",
|
||||
" with torch.no_grad():\n",
|
||||
" # Cast data to torch\n",
|
||||
" target_image = (torch.as_tensor(target_image, dtype=torch.float, device=device).permute(2,0,1) / 255)[None]\n",
|
||||
" ref_image = (torch.as_tensor(ref_image, dtype=torch.float, device=device).permute(2,0,1) / 255)[None]\n",
|
||||
"\n",
|
||||
" if normalize_input_colors:\n",
|
||||
" ref_image = (ref_image - imagenet_mean) / imagenet_std\n",
|
||||
" target_image = (target_image - imagenet_mean) / imagenet_std\n",
|
||||
"\n",
|
||||
" out, mask, _ = model(target_image, ref_image)\n",
|
||||
" # # get target\n",
|
||||
" if not is_output_normalized:\n",
|
||||
" predicted_image = model.unpatchify(out)\n",
|
||||
" else:\n",
|
||||
" # The output only contains higher order information,\n",
|
||||
" # we retrieve mean and standard deviation from the actual target image\n",
|
||||
" patchified = model.patchify(target_image)\n",
|
||||
" mean = patchified.mean(dim=-1, keepdim=True)\n",
|
||||
" var = patchified.var(dim=-1, keepdim=True)\n",
|
||||
" pred_renorm = out * (var + 1.e-6)**.5 + mean\n",
|
||||
" predicted_image = model.unpatchify(pred_renorm)\n",
|
||||
"\n",
|
||||
" image_masks = model.unpatchify(model.patchify(torch.ones_like(ref_image)) * mask[:,:,None])\n",
|
||||
" masked_target_image = (1 - image_masks) * target_image\n",
|
||||
" \n",
|
||||
" if not reconstruct_unmasked_patches:\n",
|
||||
" # Replace unmasked patches by their actual values\n",
|
||||
" predicted_image = predicted_image * image_masks + masked_target_image\n",
|
||||
"\n",
|
||||
" # Unapply color normalization\n",
|
||||
" if normalize_input_colors:\n",
|
||||
" predicted_image = predicted_image * imagenet_std + imagenet_mean\n",
|
||||
" masked_target_image = masked_target_image * imagenet_std + imagenet_mean\n",
|
||||
" \n",
|
||||
" # Cast to Numpy\n",
|
||||
" masked_target_image = np.asarray(torch.clamp(masked_target_image.squeeze(0).permute(1,2,0) * 255, 0, 255).cpu().numpy(), dtype=np.uint8)\n",
|
||||
" predicted_image = np.asarray(torch.clamp(predicted_image.squeeze(0).permute(1,2,0) * 255, 0, 255).cpu().numpy(), dtype=np.uint8)\n",
|
||||
" return masked_target_image, predicted_image"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"### Use the Habitat simulator to render images from arbitrary viewpoints (requires habitat_sim to be installed)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import os\n",
|
||||
"os.environ[\"MAGNUM_LOG\"]=\"quiet\"\n",
|
||||
"os.environ[\"HABITAT_SIM_LOG\"]=\"quiet\"\n",
|
||||
"import habitat_sim\n",
|
||||
"\n",
|
||||
"scene = \"habitat-sim-data/scene_datasets/habitat-test-scenes/skokloster-castle.glb\"\n",
|
||||
"navmesh = \"habitat-sim-data/scene_datasets/habitat-test-scenes/skokloster-castle.navmesh\"\n",
|
||||
"\n",
|
||||
"sim_cfg = habitat_sim.SimulatorConfiguration()\n",
|
||||
"if use_gpu: sim_cfg.gpu_device_id = 0\n",
|
||||
"sim_cfg.scene_id = scene\n",
|
||||
"sim_cfg.load_semantic_mesh = False\n",
|
||||
"rgb_sensor_spec = habitat_sim.CameraSensorSpec()\n",
|
||||
"rgb_sensor_spec.uuid = \"color\"\n",
|
||||
"rgb_sensor_spec.sensor_type = habitat_sim.SensorType.COLOR\n",
|
||||
"rgb_sensor_spec.resolution = (224,224)\n",
|
||||
"rgb_sensor_spec.hfov = 56.56\n",
|
||||
"rgb_sensor_spec.position = [0.0, 0.0, 0.0]\n",
|
||||
"rgb_sensor_spec.orientation = [0, 0, 0]\n",
|
||||
"agent_cfg = habitat_sim.agent.AgentConfiguration(sensor_specifications=[rgb_sensor_spec])\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"cfg = habitat_sim.Configuration(sim_cfg, [agent_cfg])\n",
|
||||
"sim = habitat_sim.Simulator(cfg)\n",
|
||||
"if navmesh is not None:\n",
|
||||
" sim.pathfinder.load_nav_mesh(navmesh)\n",
|
||||
"agent = sim.initialize_agent(agent_id=0)\n",
|
||||
"\n",
|
||||
"def sample_random_viewpoint():\n",
|
||||
" \"\"\" Sample a random viewpoint using the navmesh \"\"\"\n",
|
||||
" nav_point = sim.pathfinder.get_random_navigable_point()\n",
|
||||
" # Sample a random viewpoint height\n",
|
||||
" viewpoint_height = np.random.uniform(1.0, 1.6)\n",
|
||||
" viewpoint_position = nav_point + viewpoint_height * habitat_sim.geo.UP\n",
|
||||
" viewpoint_orientation = quaternion.from_rotation_vector(np.random.uniform(-np.pi, np.pi) * habitat_sim.geo.UP)\n",
|
||||
" return viewpoint_position, viewpoint_orientation\n",
|
||||
"\n",
|
||||
"def render_viewpoint(position, orientation):\n",
|
||||
" agent_state = habitat_sim.AgentState()\n",
|
||||
" agent_state.position = position\n",
|
||||
" agent_state.rotation = orientation\n",
|
||||
" agent.set_state(agent_state)\n",
|
||||
" viewpoint_observations = sim.get_sensor_observations(agent_ids=0)\n",
|
||||
" image = viewpoint_observations['color'][:,:,:3]\n",
|
||||
" image = np.asarray(np.clip(1.5 * np.asarray(image, dtype=float), 0, 255), dtype=np.uint8)\n",
|
||||
" return image"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"### Sample a random reference view"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"ref_position, ref_orientation = sample_random_viewpoint()\n",
|
||||
"ref_image = render_viewpoint(ref_position, ref_orientation)\n",
|
||||
"plt.clf()\n",
|
||||
"fig, axes = plt.subplots(1,1, squeeze=False, num=1)\n",
|
||||
"axes[0,0].imshow(ref_image)\n",
|
||||
"for ax in axes.flatten():\n",
|
||||
" ax.set_xticks([])\n",
|
||||
" ax.set_yticks([])"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"### Interactive cross-view completion using CroCo"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"reconstruct_unmasked_patches = False\n",
|
||||
"\n",
|
||||
"def show_demo(masking_ratio, x, y, z, panorama, elevation):\n",
|
||||
" R = quaternion.as_rotation_matrix(ref_orientation)\n",
|
||||
" target_position = ref_position + x * R[:,0] + y * R[:,1] + z * R[:,2]\n",
|
||||
" target_orientation = (ref_orientation\n",
|
||||
" * quaternion.from_rotation_vector(-elevation * np.pi/180 * habitat_sim.geo.LEFT) \n",
|
||||
" * quaternion.from_rotation_vector(-panorama * np.pi/180 * habitat_sim.geo.UP))\n",
|
||||
" \n",
|
||||
" ref_image = render_viewpoint(ref_position, ref_orientation)\n",
|
||||
" target_image = render_viewpoint(target_position, target_orientation)\n",
|
||||
"\n",
|
||||
" masked_target_image, predicted_image = process_images(ref_image, target_image, masking_ratio, reconstruct_unmasked_patches)\n",
|
||||
"\n",
|
||||
" fig, axes = plt.subplots(1,4, squeeze=True, dpi=300)\n",
|
||||
" axes[0].imshow(ref_image)\n",
|
||||
" axes[0].set_xlabel(\"Reference\")\n",
|
||||
" axes[1].imshow(masked_target_image)\n",
|
||||
" axes[1].set_xlabel(\"Masked target\")\n",
|
||||
" axes[2].imshow(predicted_image)\n",
|
||||
" axes[2].set_xlabel(\"Reconstruction\") \n",
|
||||
" axes[3].imshow(target_image)\n",
|
||||
" axes[3].set_xlabel(\"Target\")\n",
|
||||
" for ax in axes.flatten():\n",
|
||||
" ax.set_xticks([])\n",
|
||||
" ax.set_yticks([])\n",
|
||||
"\n",
|
||||
"interact(show_demo,\n",
|
||||
" masking_ratio=widgets.FloatSlider(description='masking', value=0.9, min=0.0, max=1.0),\n",
|
||||
" x=widgets.FloatSlider(value=0.0, min=-0.5, max=0.5, step=0.05),\n",
|
||||
" y=widgets.FloatSlider(value=0.0, min=-0.5, max=0.5, step=0.05),\n",
|
||||
" z=widgets.FloatSlider(value=0.0, min=-0.5, max=0.5, step=0.05),\n",
|
||||
" panorama=widgets.FloatSlider(value=0.0, min=-20, max=20, step=0.5),\n",
|
||||
" elevation=widgets.FloatSlider(value=0.0, min=-20, max=20, step=0.5));"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3 (ipykernel)",
|
||||
"language": "python",
|
||||
"name": "python3"
|
||||
},
|
||||
"language_info": {
|
||||
"codemirror_mode": {
|
||||
"name": "ipython",
|
||||
"version": 3
|
||||
},
|
||||
"file_extension": ".py",
|
||||
"mimetype": "text/x-python",
|
||||
"name": "python",
|
||||
"nbconvert_exporter": "python",
|
||||
"pygments_lexer": "ipython3",
|
||||
"version": "3.7.13"
|
||||
},
|
||||
"vscode": {
|
||||
"interpreter": {
|
||||
"hash": "f9237820cd248d7e07cb4fb9f0e4508a85d642f19d831560c0a4b61f3e907e67"
|
||||
}
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 2
|
||||
}
|
||||
+241
@@ -0,0 +1,241 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
|
||||
# --------------------------------------------------------
|
||||
# Main encoder/decoder blocks
|
||||
# --------------------------------------------------------
|
||||
# References:
|
||||
# timm
|
||||
# https://github.com/rwightman/pytorch-image-models/blob/master/timm/models/vision_transformer.py
|
||||
# https://github.com/rwightman/pytorch-image-models/blob/master/timm/models/layers/helpers.py
|
||||
# https://github.com/rwightman/pytorch-image-models/blob/master/timm/models/layers/drop.py
|
||||
# https://github.com/rwightman/pytorch-image-models/blob/master/timm/models/layers/mlp.py
|
||||
# https://github.com/rwightman/pytorch-image-models/blob/master/timm/models/layers/patch_embed.py
|
||||
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
|
||||
from itertools import repeat
|
||||
import collections.abc
|
||||
|
||||
|
||||
def _ntuple(n):
|
||||
def parse(x):
|
||||
if isinstance(x, collections.abc.Iterable) and not isinstance(x, str):
|
||||
return x
|
||||
return tuple(repeat(x, n))
|
||||
return parse
|
||||
to_2tuple = _ntuple(2)
|
||||
|
||||
def drop_path(x, drop_prob: float = 0., training: bool = False, scale_by_keep: bool = True):
|
||||
"""Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).
|
||||
"""
|
||||
if drop_prob == 0. or not training:
|
||||
return x
|
||||
keep_prob = 1 - drop_prob
|
||||
shape = (x.shape[0],) + (1,) * (x.ndim - 1) # work with diff dim tensors, not just 2D ConvNets
|
||||
random_tensor = x.new_empty(shape).bernoulli_(keep_prob)
|
||||
if keep_prob > 0.0 and scale_by_keep:
|
||||
random_tensor.div_(keep_prob)
|
||||
return x * random_tensor
|
||||
|
||||
class DropPath(nn.Module):
|
||||
"""Drop paths (Stochastic Depth) per sample (when applied in main path of residual blocks).
|
||||
"""
|
||||
def __init__(self, drop_prob: float = 0., scale_by_keep: bool = True):
|
||||
super(DropPath, self).__init__()
|
||||
self.drop_prob = drop_prob
|
||||
self.scale_by_keep = scale_by_keep
|
||||
|
||||
def forward(self, x):
|
||||
return drop_path(x, self.drop_prob, self.training, self.scale_by_keep)
|
||||
|
||||
def extra_repr(self):
|
||||
return f'drop_prob={round(self.drop_prob,3):0.3f}'
|
||||
|
||||
class Mlp(nn.Module):
|
||||
""" MLP as used in Vision Transformer, MLP-Mixer and related networks"""
|
||||
def __init__(self, in_features, hidden_features=None, out_features=None, act_layer=nn.GELU, bias=True, drop=0.):
|
||||
super().__init__()
|
||||
out_features = out_features or in_features
|
||||
hidden_features = hidden_features or in_features
|
||||
bias = to_2tuple(bias)
|
||||
drop_probs = to_2tuple(drop)
|
||||
|
||||
self.fc1 = nn.Linear(in_features, hidden_features, bias=bias[0])
|
||||
self.act = act_layer()
|
||||
self.drop1 = nn.Dropout(drop_probs[0])
|
||||
self.fc2 = nn.Linear(hidden_features, out_features, bias=bias[1])
|
||||
self.drop2 = nn.Dropout(drop_probs[1])
|
||||
|
||||
def forward(self, x):
|
||||
x = self.fc1(x)
|
||||
x = self.act(x)
|
||||
x = self.drop1(x)
|
||||
x = self.fc2(x)
|
||||
x = self.drop2(x)
|
||||
return x
|
||||
|
||||
class Attention(nn.Module):
|
||||
|
||||
def __init__(self, dim, rope=None, num_heads=8, qkv_bias=False, attn_drop=0., proj_drop=0.):
|
||||
super().__init__()
|
||||
self.num_heads = num_heads
|
||||
head_dim = dim // num_heads
|
||||
self.scale = head_dim ** -0.5
|
||||
self.qkv = nn.Linear(dim, dim * 3, bias=qkv_bias)
|
||||
self.attn_drop = nn.Dropout(attn_drop)
|
||||
self.proj = nn.Linear(dim, dim)
|
||||
self.proj_drop = nn.Dropout(proj_drop)
|
||||
self.rope = rope
|
||||
|
||||
def forward(self, x, xpos):
|
||||
B, N, C = x.shape
|
||||
|
||||
qkv = self.qkv(x).reshape(B, N, 3, self.num_heads, C // self.num_heads).transpose(1,3)
|
||||
q, k, v = [qkv[:,:,i] for i in range(3)]
|
||||
# q,k,v = qkv.unbind(2) # make torchscript happy (cannot use tensor as tuple)
|
||||
|
||||
if self.rope is not None:
|
||||
q = self.rope(q, xpos)
|
||||
k = self.rope(k, xpos)
|
||||
|
||||
attn = (q @ k.transpose(-2, -1)) * self.scale
|
||||
attn = attn.softmax(dim=-1)
|
||||
attn = self.attn_drop(attn)
|
||||
|
||||
x = (attn @ v).transpose(1, 2).reshape(B, N, C)
|
||||
x = self.proj(x)
|
||||
x = self.proj_drop(x)
|
||||
return x
|
||||
|
||||
class Block(nn.Module):
|
||||
|
||||
def __init__(self, dim, num_heads, mlp_ratio=4., qkv_bias=False, drop=0., attn_drop=0.,
|
||||
drop_path=0., act_layer=nn.GELU, norm_layer=nn.LayerNorm, rope=None):
|
||||
super().__init__()
|
||||
self.norm1 = norm_layer(dim)
|
||||
self.attn = Attention(dim, rope=rope, num_heads=num_heads, qkv_bias=qkv_bias, attn_drop=attn_drop, proj_drop=drop)
|
||||
# NOTE: drop path for stochastic depth, we shall see if this is better than dropout here
|
||||
self.drop_path = DropPath(drop_path) if drop_path > 0. else nn.Identity()
|
||||
self.norm2 = norm_layer(dim)
|
||||
mlp_hidden_dim = int(dim * mlp_ratio)
|
||||
self.mlp = Mlp(in_features=dim, hidden_features=mlp_hidden_dim, act_layer=act_layer, drop=drop)
|
||||
|
||||
def forward(self, x, xpos):
|
||||
x = x + self.drop_path(self.attn(self.norm1(x), xpos))
|
||||
x = x + self.drop_path(self.mlp(self.norm2(x)))
|
||||
return x
|
||||
|
||||
class CrossAttention(nn.Module):
|
||||
|
||||
def __init__(self, dim, rope=None, num_heads=8, qkv_bias=False, attn_drop=0., proj_drop=0.):
|
||||
super().__init__()
|
||||
self.num_heads = num_heads
|
||||
head_dim = dim // num_heads
|
||||
self.scale = head_dim ** -0.5
|
||||
|
||||
self.projq = nn.Linear(dim, dim, bias=qkv_bias)
|
||||
self.projk = nn.Linear(dim, dim, bias=qkv_bias)
|
||||
self.projv = nn.Linear(dim, dim, bias=qkv_bias)
|
||||
self.attn_drop = nn.Dropout(attn_drop)
|
||||
self.proj = nn.Linear(dim, dim)
|
||||
self.proj_drop = nn.Dropout(proj_drop)
|
||||
|
||||
self.rope = rope
|
||||
|
||||
def forward(self, query, key, value, qpos, kpos):
|
||||
B, Nq, C = query.shape
|
||||
Nk = key.shape[1]
|
||||
Nv = value.shape[1]
|
||||
|
||||
q = self.projq(query).reshape(B,Nq,self.num_heads, C// self.num_heads).permute(0, 2, 1, 3)
|
||||
k = self.projk(key).reshape(B,Nk,self.num_heads, C// self.num_heads).permute(0, 2, 1, 3)
|
||||
v = self.projv(value).reshape(B,Nv,self.num_heads, C// self.num_heads).permute(0, 2, 1, 3)
|
||||
|
||||
if self.rope is not None:
|
||||
q = self.rope(q, qpos)
|
||||
k = self.rope(k, kpos)
|
||||
|
||||
attn = (q @ k.transpose(-2, -1)) * self.scale
|
||||
attn = attn.softmax(dim=-1)
|
||||
attn = self.attn_drop(attn)
|
||||
|
||||
x = (attn @ v).transpose(1, 2).reshape(B, Nq, C)
|
||||
x = self.proj(x)
|
||||
x = self.proj_drop(x)
|
||||
return x
|
||||
|
||||
class DecoderBlock(nn.Module):
|
||||
|
||||
def __init__(self, dim, num_heads, mlp_ratio=4., qkv_bias=False, drop=0., attn_drop=0.,
|
||||
drop_path=0., act_layer=nn.GELU, norm_layer=nn.LayerNorm, norm_mem=True, rope=None):
|
||||
super().__init__()
|
||||
self.norm1 = norm_layer(dim)
|
||||
self.attn = Attention(dim, rope=rope, num_heads=num_heads, qkv_bias=qkv_bias, attn_drop=attn_drop, proj_drop=drop)
|
||||
self.cross_attn = CrossAttention(dim, rope=rope, num_heads=num_heads, qkv_bias=qkv_bias, attn_drop=attn_drop, proj_drop=drop)
|
||||
self.drop_path = DropPath(drop_path) if drop_path > 0. else nn.Identity()
|
||||
self.norm2 = norm_layer(dim)
|
||||
self.norm3 = norm_layer(dim)
|
||||
mlp_hidden_dim = int(dim * mlp_ratio)
|
||||
self.mlp = Mlp(in_features=dim, hidden_features=mlp_hidden_dim, act_layer=act_layer, drop=drop)
|
||||
self.norm_y = norm_layer(dim) if norm_mem else nn.Identity()
|
||||
|
||||
def forward(self, x, y, xpos, ypos):
|
||||
x = x + self.drop_path(self.attn(self.norm1(x), xpos))
|
||||
y_ = self.norm_y(y)
|
||||
x = x + self.drop_path(self.cross_attn(self.norm2(x), y_, y_, xpos, ypos))
|
||||
x = x + self.drop_path(self.mlp(self.norm3(x)))
|
||||
return x, y
|
||||
|
||||
|
||||
# patch embedding
|
||||
class PositionGetter(object):
|
||||
""" return positions of patches """
|
||||
|
||||
def __init__(self):
|
||||
self.cache_positions = {}
|
||||
|
||||
def __call__(self, b, h, w, device):
|
||||
if not (h,w) in self.cache_positions:
|
||||
x = torch.arange(w, device=device)
|
||||
y = torch.arange(h, device=device)
|
||||
self.cache_positions[h,w] = torch.cartesian_prod(y, x) # (h, w, 2)
|
||||
pos = self.cache_positions[h,w].view(1, h*w, 2).expand(b, -1, 2).clone()
|
||||
return pos
|
||||
|
||||
class PatchEmbed(nn.Module):
|
||||
""" just adding _init_weights + position getter compared to timm.models.layers.patch_embed.PatchEmbed"""
|
||||
|
||||
def __init__(self, img_size=224, patch_size=16, in_chans=3, embed_dim=768, norm_layer=None, flatten=True):
|
||||
super().__init__()
|
||||
img_size = to_2tuple(img_size)
|
||||
patch_size = to_2tuple(patch_size)
|
||||
self.img_size = img_size
|
||||
self.patch_size = patch_size
|
||||
self.grid_size = (img_size[0] // patch_size[0], img_size[1] // patch_size[1])
|
||||
self.num_patches = self.grid_size[0] * self.grid_size[1]
|
||||
self.flatten = flatten
|
||||
|
||||
self.proj = nn.Conv2d(in_chans, embed_dim, kernel_size=patch_size, stride=patch_size)
|
||||
self.norm = norm_layer(embed_dim) if norm_layer else nn.Identity()
|
||||
|
||||
self.position_getter = PositionGetter()
|
||||
|
||||
def forward(self, x):
|
||||
B, C, H, W = x.shape
|
||||
torch._assert(H == self.img_size[0], f"Input image height ({H}) doesn't match model ({self.img_size[0]}).")
|
||||
torch._assert(W == self.img_size[1], f"Input image width ({W}) doesn't match model ({self.img_size[1]}).")
|
||||
x = self.proj(x)
|
||||
pos = self.position_getter(B, x.size(2), x.size(3), x.device)
|
||||
if self.flatten:
|
||||
x = x.flatten(2).transpose(1, 2) # BCHW -> BNC
|
||||
x = self.norm(x)
|
||||
return x, pos
|
||||
|
||||
def _init_weights(self):
|
||||
w = self.proj.weight.data
|
||||
torch.nn.init.xavier_uniform_(w.view([w.shape[0], -1]))
|
||||
|
||||
@@ -0,0 +1,37 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# Criterion to train CroCo
|
||||
# --------------------------------------------------------
|
||||
# References:
|
||||
# MAE: https://github.com/facebookresearch/mae
|
||||
# --------------------------------------------------------
|
||||
|
||||
import torch
|
||||
|
||||
class MaskedMSE(torch.nn.Module):
|
||||
|
||||
def __init__(self, norm_pix_loss=False, masked=True):
|
||||
"""
|
||||
norm_pix_loss: normalize each patch by their pixel mean and variance
|
||||
masked: compute loss over the masked patches only
|
||||
"""
|
||||
super().__init__()
|
||||
self.norm_pix_loss = norm_pix_loss
|
||||
self.masked = masked
|
||||
|
||||
def forward(self, pred, mask, target):
|
||||
|
||||
if self.norm_pix_loss:
|
||||
mean = target.mean(dim=-1, keepdim=True)
|
||||
var = target.var(dim=-1, keepdim=True)
|
||||
target = (target - mean) / (var + 1.e-6)**.5
|
||||
|
||||
loss = (pred - target) ** 2
|
||||
loss = loss.mean(dim=-1) # [N, L], mean loss per patch
|
||||
if self.masked:
|
||||
loss = (loss * mask).sum() / mask.sum() # mean loss on masked patches
|
||||
else:
|
||||
loss = loss.mean() # mean loss
|
||||
return loss
|
||||
+249
@@ -0,0 +1,249 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
|
||||
# --------------------------------------------------------
|
||||
# CroCo model during pretraining
|
||||
# --------------------------------------------------------
|
||||
|
||||
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
torch.backends.cuda.matmul.allow_tf32 = True # for gpu >= Ampere and pytorch >= 1.12
|
||||
from functools import partial
|
||||
|
||||
from models.blocks import Block, DecoderBlock, PatchEmbed
|
||||
from models.pos_embed import get_2d_sincos_pos_embed, RoPE2D
|
||||
from models.masking import RandomMask
|
||||
|
||||
|
||||
class CroCoNet(nn.Module):
|
||||
|
||||
def __init__(self,
|
||||
img_size=224, # input image size
|
||||
patch_size=16, # patch_size
|
||||
mask_ratio=0.9, # ratios of masked tokens
|
||||
enc_embed_dim=768, # encoder feature dimension
|
||||
enc_depth=12, # encoder depth
|
||||
enc_num_heads=12, # encoder number of heads in the transformer block
|
||||
dec_embed_dim=512, # decoder feature dimension
|
||||
dec_depth=8, # decoder depth
|
||||
dec_num_heads=16, # decoder number of heads in the transformer block
|
||||
mlp_ratio=4,
|
||||
norm_layer=partial(nn.LayerNorm, eps=1e-6),
|
||||
norm_im2_in_dec=True, # whether to apply normalization of the 'memory' = (second image) in the decoder
|
||||
pos_embed='cosine', # positional embedding (either cosine or RoPE100)
|
||||
):
|
||||
|
||||
super(CroCoNet, self).__init__()
|
||||
|
||||
# patch embeddings (with initialization done as in MAE)
|
||||
self._set_patch_embed(img_size, patch_size, enc_embed_dim)
|
||||
|
||||
# mask generations
|
||||
self._set_mask_generator(self.patch_embed.num_patches, mask_ratio)
|
||||
|
||||
self.pos_embed = pos_embed
|
||||
if pos_embed=='cosine':
|
||||
# positional embedding of the encoder
|
||||
enc_pos_embed = get_2d_sincos_pos_embed(enc_embed_dim, int(self.patch_embed.num_patches**.5), n_cls_token=0)
|
||||
self.register_buffer('enc_pos_embed', torch.from_numpy(enc_pos_embed).float())
|
||||
# positional embedding of the decoder
|
||||
dec_pos_embed = get_2d_sincos_pos_embed(dec_embed_dim, int(self.patch_embed.num_patches**.5), n_cls_token=0)
|
||||
self.register_buffer('dec_pos_embed', torch.from_numpy(dec_pos_embed).float())
|
||||
# pos embedding in each block
|
||||
self.rope = None # nothing for cosine
|
||||
elif pos_embed.startswith('RoPE'): # eg RoPE100
|
||||
self.enc_pos_embed = None # nothing to add in the encoder with RoPE
|
||||
self.dec_pos_embed = None # nothing to add in the decoder with RoPE
|
||||
if RoPE2D is None: raise ImportError("Cannot find cuRoPE2D, please install it following the README instructions")
|
||||
freq = float(pos_embed[len('RoPE'):])
|
||||
self.rope = RoPE2D(freq=freq)
|
||||
else:
|
||||
raise NotImplementedError('Unknown pos_embed '+pos_embed)
|
||||
|
||||
# transformer for the encoder
|
||||
self.enc_depth = enc_depth
|
||||
self.enc_embed_dim = enc_embed_dim
|
||||
self.enc_blocks = nn.ModuleList([
|
||||
Block(enc_embed_dim, enc_num_heads, mlp_ratio, qkv_bias=True, norm_layer=norm_layer, rope=self.rope)
|
||||
for i in range(enc_depth)])
|
||||
self.enc_norm = norm_layer(enc_embed_dim)
|
||||
|
||||
# masked tokens
|
||||
self._set_mask_token(dec_embed_dim)
|
||||
|
||||
# decoder
|
||||
self._set_decoder(enc_embed_dim, dec_embed_dim, dec_num_heads, dec_depth, mlp_ratio, norm_layer, norm_im2_in_dec)
|
||||
|
||||
# prediction head
|
||||
self._set_prediction_head(dec_embed_dim, patch_size)
|
||||
|
||||
# initializer weights
|
||||
self.initialize_weights()
|
||||
|
||||
def _set_patch_embed(self, img_size=224, patch_size=16, enc_embed_dim=768):
|
||||
self.patch_embed = PatchEmbed(img_size, patch_size, 3, enc_embed_dim)
|
||||
|
||||
def _set_mask_generator(self, num_patches, mask_ratio):
|
||||
self.mask_generator = RandomMask(num_patches, mask_ratio)
|
||||
|
||||
def _set_mask_token(self, dec_embed_dim):
|
||||
self.mask_token = nn.Parameter(torch.zeros(1, 1, dec_embed_dim))
|
||||
|
||||
def _set_decoder(self, enc_embed_dim, dec_embed_dim, dec_num_heads, dec_depth, mlp_ratio, norm_layer, norm_im2_in_dec):
|
||||
self.dec_depth = dec_depth
|
||||
self.dec_embed_dim = dec_embed_dim
|
||||
# transfer from encoder to decoder
|
||||
self.decoder_embed = nn.Linear(enc_embed_dim, dec_embed_dim, bias=True)
|
||||
# transformer for the decoder
|
||||
self.dec_blocks = nn.ModuleList([
|
||||
DecoderBlock(dec_embed_dim, dec_num_heads, mlp_ratio=mlp_ratio, qkv_bias=True, norm_layer=norm_layer, norm_mem=norm_im2_in_dec, rope=self.rope)
|
||||
for i in range(dec_depth)])
|
||||
# final norm layer
|
||||
self.dec_norm = norm_layer(dec_embed_dim)
|
||||
|
||||
def _set_prediction_head(self, dec_embed_dim, patch_size):
|
||||
self.prediction_head = nn.Linear(dec_embed_dim, patch_size**2 * 3, bias=True)
|
||||
|
||||
|
||||
def initialize_weights(self):
|
||||
# patch embed
|
||||
self.patch_embed._init_weights()
|
||||
# mask tokens
|
||||
if self.mask_token is not None: torch.nn.init.normal_(self.mask_token, std=.02)
|
||||
# linears and layer norms
|
||||
self.apply(self._init_weights)
|
||||
|
||||
def _init_weights(self, m):
|
||||
if isinstance(m, nn.Linear):
|
||||
# we use xavier_uniform following official JAX ViT:
|
||||
torch.nn.init.xavier_uniform_(m.weight)
|
||||
if isinstance(m, nn.Linear) and m.bias is not None:
|
||||
nn.init.constant_(m.bias, 0)
|
||||
elif isinstance(m, nn.LayerNorm):
|
||||
nn.init.constant_(m.bias, 0)
|
||||
nn.init.constant_(m.weight, 1.0)
|
||||
|
||||
def _encode_image(self, image, do_mask=False, return_all_blocks=False):
|
||||
"""
|
||||
image has B x 3 x img_size x img_size
|
||||
do_mask: whether to perform masking or not
|
||||
return_all_blocks: if True, return the features at the end of every block
|
||||
instead of just the features from the last block (eg for some prediction heads)
|
||||
"""
|
||||
# embed the image into patches (x has size B x Npatches x C)
|
||||
# and get position if each return patch (pos has size B x Npatches x 2)
|
||||
x, pos = self.patch_embed(image)
|
||||
# add positional embedding without cls token
|
||||
if self.enc_pos_embed is not None:
|
||||
x = x + self.enc_pos_embed[None,...]
|
||||
# apply masking
|
||||
B,N,C = x.size()
|
||||
if do_mask:
|
||||
masks = self.mask_generator(x)
|
||||
x = x[~masks].view(B, -1, C)
|
||||
posvis = pos[~masks].view(B, -1, 2)
|
||||
else:
|
||||
B,N,C = x.size()
|
||||
masks = torch.zeros((B,N), dtype=bool)
|
||||
posvis = pos
|
||||
# now apply the transformer encoder and normalization
|
||||
if return_all_blocks:
|
||||
out = []
|
||||
for blk in self.enc_blocks:
|
||||
x = blk(x, posvis)
|
||||
out.append(x)
|
||||
out[-1] = self.enc_norm(out[-1])
|
||||
return out, pos, masks
|
||||
else:
|
||||
for blk in self.enc_blocks:
|
||||
x = blk(x, posvis)
|
||||
x = self.enc_norm(x)
|
||||
return x, pos, masks
|
||||
|
||||
def _decoder(self, feat1, pos1, masks1, feat2, pos2, return_all_blocks=False):
|
||||
"""
|
||||
return_all_blocks: if True, return the features at the end of every block
|
||||
instead of just the features from the last block (eg for some prediction heads)
|
||||
|
||||
masks1 can be None => assume image1 fully visible
|
||||
"""
|
||||
# encoder to decoder layer
|
||||
visf1 = self.decoder_embed(feat1)
|
||||
f2 = self.decoder_embed(feat2)
|
||||
# append masked tokens to the sequence
|
||||
B,Nenc,C = visf1.size()
|
||||
if masks1 is None: # downstreams
|
||||
f1_ = visf1
|
||||
else: # pretraining
|
||||
Ntotal = masks1.size(1)
|
||||
f1_ = self.mask_token.repeat(B, Ntotal, 1).to(dtype=visf1.dtype)
|
||||
f1_[~masks1] = visf1.view(B * Nenc, C)
|
||||
# add positional embedding
|
||||
if self.dec_pos_embed is not None:
|
||||
f1_ = f1_ + self.dec_pos_embed
|
||||
f2 = f2 + self.dec_pos_embed
|
||||
# apply Transformer blocks
|
||||
out = f1_
|
||||
out2 = f2
|
||||
if return_all_blocks:
|
||||
_out, out = out, []
|
||||
for blk in self.dec_blocks:
|
||||
_out, out2 = blk(_out, out2, pos1, pos2)
|
||||
out.append(_out)
|
||||
out[-1] = self.dec_norm(out[-1])
|
||||
else:
|
||||
for blk in self.dec_blocks:
|
||||
out, out2 = blk(out, out2, pos1, pos2)
|
||||
out = self.dec_norm(out)
|
||||
return out
|
||||
|
||||
def patchify(self, imgs):
|
||||
"""
|
||||
imgs: (B, 3, H, W)
|
||||
x: (B, L, patch_size**2 *3)
|
||||
"""
|
||||
p = self.patch_embed.patch_size[0]
|
||||
assert imgs.shape[2] == imgs.shape[3] and imgs.shape[2] % p == 0
|
||||
|
||||
h = w = imgs.shape[2] // p
|
||||
x = imgs.reshape(shape=(imgs.shape[0], 3, h, p, w, p))
|
||||
x = torch.einsum('nchpwq->nhwpqc', x)
|
||||
x = x.reshape(shape=(imgs.shape[0], h * w, p**2 * 3))
|
||||
|
||||
return x
|
||||
|
||||
def unpatchify(self, x, channels=3):
|
||||
"""
|
||||
x: (N, L, patch_size**2 *channels)
|
||||
imgs: (N, 3, H, W)
|
||||
"""
|
||||
patch_size = self.patch_embed.patch_size[0]
|
||||
h = w = int(x.shape[1]**.5)
|
||||
assert h * w == x.shape[1]
|
||||
x = x.reshape(shape=(x.shape[0], h, w, patch_size, patch_size, channels))
|
||||
x = torch.einsum('nhwpqc->nchpwq', x)
|
||||
imgs = x.reshape(shape=(x.shape[0], channels, h * patch_size, h * patch_size))
|
||||
return imgs
|
||||
|
||||
def forward(self, img1, img2):
|
||||
"""
|
||||
img1: tensor of size B x 3 x img_size x img_size
|
||||
img2: tensor of size B x 3 x img_size x img_size
|
||||
|
||||
out will be B x N x (3*patch_size*patch_size)
|
||||
masks are also returned as B x N just in case
|
||||
"""
|
||||
# encoder of the masked first image
|
||||
feat1, pos1, mask1 = self._encode_image(img1, do_mask=True)
|
||||
# encoder of the second image
|
||||
feat2, pos2, _ = self._encode_image(img2, do_mask=False)
|
||||
# decoder
|
||||
decfeat = self._decoder(feat1, pos1, mask1, feat2, pos2)
|
||||
# prediction head
|
||||
out = self.prediction_head(decfeat)
|
||||
# get target
|
||||
target = self.patchify(img1)
|
||||
return out, mask1, target
|
||||
@@ -0,0 +1,122 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
# --------------------------------------------------------
|
||||
# CroCo model for downstream tasks
|
||||
# --------------------------------------------------------
|
||||
|
||||
import torch
|
||||
|
||||
from .croco import CroCoNet
|
||||
|
||||
|
||||
def croco_args_from_ckpt(ckpt):
|
||||
if 'croco_kwargs' in ckpt: # CroCo v2 released models
|
||||
return ckpt['croco_kwargs']
|
||||
elif 'args' in ckpt and hasattr(ckpt['args'], 'model'): # pretrained using the official code release
|
||||
s = ckpt['args'].model # eg "CroCoNet(enc_embed_dim=1024, enc_num_heads=16, enc_depth=24)"
|
||||
assert s.startswith('CroCoNet(')
|
||||
return eval('dict'+s[len('CroCoNet'):]) # transform it into the string of a dictionary and evaluate it
|
||||
else: # CroCo v1 released models
|
||||
return dict()
|
||||
|
||||
class CroCoDownstreamMonocularEncoder(CroCoNet):
|
||||
|
||||
def __init__(self,
|
||||
head,
|
||||
**kwargs):
|
||||
""" Build network for monocular downstream task, only using the encoder.
|
||||
It takes an extra argument head, that is called with the features
|
||||
and a dictionary img_info containing 'width' and 'height' keys
|
||||
The head is setup with the croconet arguments in this init function
|
||||
NOTE: It works by *calling super().__init__() but with redefined setters
|
||||
|
||||
"""
|
||||
super(CroCoDownstreamMonocularEncoder, self).__init__(**kwargs)
|
||||
head.setup(self)
|
||||
self.head = head
|
||||
|
||||
def _set_mask_generator(self, *args, **kwargs):
|
||||
""" No mask generator """
|
||||
return
|
||||
|
||||
def _set_mask_token(self, *args, **kwargs):
|
||||
""" No mask token """
|
||||
self.mask_token = None
|
||||
return
|
||||
|
||||
def _set_decoder(self, *args, **kwargs):
|
||||
""" No decoder """
|
||||
return
|
||||
|
||||
def _set_prediction_head(self, *args, **kwargs):
|
||||
""" No 'prediction head' for downstream tasks."""
|
||||
return
|
||||
|
||||
def forward(self, img):
|
||||
"""
|
||||
img if of size batch_size x 3 x h x w
|
||||
"""
|
||||
B, C, H, W = img.size()
|
||||
img_info = {'height': H, 'width': W}
|
||||
need_all_layers = hasattr(self.head, 'return_all_blocks') and self.head.return_all_blocks
|
||||
out, _, _ = self._encode_image(img, do_mask=False, return_all_blocks=need_all_layers)
|
||||
return self.head(out, img_info)
|
||||
|
||||
|
||||
class CroCoDownstreamBinocular(CroCoNet):
|
||||
|
||||
def __init__(self,
|
||||
head,
|
||||
**kwargs):
|
||||
""" Build network for binocular downstream task
|
||||
It takes an extra argument head, that is called with the features
|
||||
and a dictionary img_info containing 'width' and 'height' keys
|
||||
The head is setup with the croconet arguments in this init function
|
||||
"""
|
||||
super(CroCoDownstreamBinocular, self).__init__(**kwargs)
|
||||
head.setup(self)
|
||||
self.head = head
|
||||
|
||||
def _set_mask_generator(self, *args, **kwargs):
|
||||
""" No mask generator """
|
||||
return
|
||||
|
||||
def _set_mask_token(self, *args, **kwargs):
|
||||
""" No mask token """
|
||||
self.mask_token = None
|
||||
return
|
||||
|
||||
def _set_prediction_head(self, *args, **kwargs):
|
||||
""" No prediction head for downstream tasks, define your own head """
|
||||
return
|
||||
|
||||
def encode_image_pairs(self, img1, img2, return_all_blocks=False):
|
||||
""" run encoder for a pair of images
|
||||
it is actually ~5% faster to concatenate the images along the batch dimension
|
||||
than to encode them separately
|
||||
"""
|
||||
## the two commented lines below is the naive version with separate encoding
|
||||
#out, pos, _ = self._encode_image(img1, do_mask=False, return_all_blocks=return_all_blocks)
|
||||
#out2, pos2, _ = self._encode_image(img2, do_mask=False, return_all_blocks=False)
|
||||
## and now the faster version
|
||||
out, pos, _ = self._encode_image( torch.cat( (img1,img2), dim=0), do_mask=False, return_all_blocks=return_all_blocks )
|
||||
if return_all_blocks:
|
||||
out,out2 = list(map(list, zip(*[o.chunk(2, dim=0) for o in out])))
|
||||
out2 = out2[-1]
|
||||
else:
|
||||
out,out2 = out.chunk(2, dim=0)
|
||||
pos,pos2 = pos.chunk(2, dim=0)
|
||||
return out, out2, pos, pos2
|
||||
|
||||
def forward(self, img1, img2):
|
||||
B, C, H, W = img1.size()
|
||||
img_info = {'height': H, 'width': W}
|
||||
return_all_blocks = hasattr(self.head, 'return_all_blocks') and self.head.return_all_blocks
|
||||
out, out2, pos, pos2 = self.encode_image_pairs(img1, img2, return_all_blocks=return_all_blocks)
|
||||
if return_all_blocks:
|
||||
decout = self._decoder(out[-1], pos, None, out2, pos2, return_all_blocks=return_all_blocks)
|
||||
decout = out+decout
|
||||
else:
|
||||
decout = self._decoder(out, pos, None, out2, pos2, return_all_blocks=return_all_blocks)
|
||||
return self.head(decout, img_info)
|
||||
@@ -0,0 +1,4 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
from .curope2d import cuRoPE2D
|
||||
Vendored
+34
@@ -0,0 +1,34 @@
|
||||
ninja_required_version = 1.3
|
||||
cxx = g++
|
||||
nvcc = /usr/local/cuda/bin/nvcc
|
||||
|
||||
cflags = -pthread -B /root/anaconda3/envs/3studio/compiler_compat -Wl,--sysroot=/ -Wsign-compare -DNDEBUG -g -fwrapv -O3 -Wall -Wstrict-prototypes -fPIC -I/root/anaconda3/envs/3studio/lib/python3.8/site-packages/torch/include -I/root/anaconda3/envs/3studio/lib/python3.8/site-packages/torch/include/torch/csrc/api/include -I/root/anaconda3/envs/3studio/lib/python3.8/site-packages/torch/include/TH -I/root/anaconda3/envs/3studio/lib/python3.8/site-packages/torch/include/THC -I/usr/local/cuda/include -I/root/anaconda3/envs/3studio/include/python3.8 -c
|
||||
post_cflags = -O3 -DTORCH_API_INCLUDE_EXTENSION_H '-DPYBIND11_COMPILER_TYPE="_gcc"' '-DPYBIND11_STDLIB="_libstdcpp"' '-DPYBIND11_BUILD_ABI="_cxxabi1011"' -DTORCH_EXTENSION_NAME=curope -D_GLIBCXX_USE_CXX11_ABI=0 -std=c++17
|
||||
cuda_cflags = -I/root/anaconda3/envs/3studio/lib/python3.8/site-packages/torch/include -I/root/anaconda3/envs/3studio/lib/python3.8/site-packages/torch/include/torch/csrc/api/include -I/root/anaconda3/envs/3studio/lib/python3.8/site-packages/torch/include/TH -I/root/anaconda3/envs/3studio/lib/python3.8/site-packages/torch/include/THC -I/usr/local/cuda/include -I/root/anaconda3/envs/3studio/include/python3.8 -c
|
||||
cuda_post_cflags = -D__CUDA_NO_HALF_OPERATORS__ -D__CUDA_NO_HALF_CONVERSIONS__ -D__CUDA_NO_BFLOAT16_CONVERSIONS__ -D__CUDA_NO_HALF2_OPERATORS__ --expt-relaxed-constexpr --compiler-options ''"'"'-fPIC'"'"'' -O3 --ptxas-options=-v --use_fast_math -gencode arch=compute_37,code=sm_37 -gencode arch=compute_50,code=sm_50 -gencode arch=compute_60,code=sm_60 -gencode arch=compute_70,code=sm_70 -gencode arch=compute_75,code=sm_75 -gencode arch=compute_80,code=sm_80 -gencode arch=compute_86,code=sm_86 -DTORCH_API_INCLUDE_EXTENSION_H '-DPYBIND11_COMPILER_TYPE="_gcc"' '-DPYBIND11_STDLIB="_libstdcpp"' '-DPYBIND11_BUILD_ABI="_cxxabi1011"' -DTORCH_EXTENSION_NAME=curope -D_GLIBCXX_USE_CXX11_ABI=0 -std=c++17
|
||||
cuda_dlink_post_cflags =
|
||||
ldflags =
|
||||
|
||||
rule compile
|
||||
command = $cxx -MMD -MF $out.d $cflags -c $in -o $out $post_cflags
|
||||
depfile = $out.d
|
||||
deps = gcc
|
||||
|
||||
rule cuda_compile
|
||||
depfile = $out.d
|
||||
deps = gcc
|
||||
command = $nvcc $cuda_cflags -c $in -o $out $cuda_post_cflags
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
build /apdcephfs_cq10/share_1290939/karmyu/dust3r-gaussian-splatting/dust3r/croco/models/curope/build/temp.linux-x86_64-cpython-38/curope.o: compile /apdcephfs_cq10/share_1290939/karmyu/dust3r-gaussian-splatting/dust3r/croco/models/curope/curope.cpp
|
||||
build /apdcephfs_cq10/share_1290939/karmyu/dust3r-gaussian-splatting/dust3r/croco/models/curope/build/temp.linux-x86_64-cpython-38/kernels.o: cuda_compile /apdcephfs_cq10/share_1290939/karmyu/dust3r-gaussian-splatting/dust3r/croco/models/curope/kernels.cu
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,69 @@
|
||||
/*
|
||||
Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
*/
|
||||
|
||||
#include <torch/extension.h>
|
||||
|
||||
// forward declaration
|
||||
void rope_2d_cuda( torch::Tensor tokens, const torch::Tensor pos, const float base, const float fwd );
|
||||
|
||||
void rope_2d_cpu( torch::Tensor tokens, const torch::Tensor positions, const float base, const float fwd )
|
||||
{
|
||||
const int B = tokens.size(0);
|
||||
const int N = tokens.size(1);
|
||||
const int H = tokens.size(2);
|
||||
const int D = tokens.size(3) / 4;
|
||||
|
||||
auto tok = tokens.accessor<float, 4>();
|
||||
auto pos = positions.accessor<int64_t, 3>();
|
||||
|
||||
for (int b = 0; b < B; b++) {
|
||||
for (int x = 0; x < 2; x++) { // y and then x (2d)
|
||||
for (int n = 0; n < N; n++) {
|
||||
|
||||
// grab the token position
|
||||
const int p = pos[b][n][x];
|
||||
|
||||
for (int h = 0; h < H; h++) {
|
||||
for (int d = 0; d < D; d++) {
|
||||
// grab the two values
|
||||
float u = tok[b][n][h][d+0+x*2*D];
|
||||
float v = tok[b][n][h][d+D+x*2*D];
|
||||
|
||||
// grab the cos,sin
|
||||
const float inv_freq = fwd * p / powf(base, d/float(D));
|
||||
float c = cosf(inv_freq);
|
||||
float s = sinf(inv_freq);
|
||||
|
||||
// write the result
|
||||
tok[b][n][h][d+0+x*2*D] = u*c - v*s;
|
||||
tok[b][n][h][d+D+x*2*D] = v*c + u*s;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
void rope_2d( torch::Tensor tokens, // B,N,H,D
|
||||
const torch::Tensor positions, // B,N,2
|
||||
const float base,
|
||||
const float fwd )
|
||||
{
|
||||
TORCH_CHECK(tokens.dim() == 4, "tokens must have 4 dimensions");
|
||||
TORCH_CHECK(positions.dim() == 3, "positions must have 3 dimensions");
|
||||
TORCH_CHECK(tokens.size(0) == positions.size(0), "batch size differs between tokens & positions");
|
||||
TORCH_CHECK(tokens.size(1) == positions.size(1), "seq_length differs between tokens & positions");
|
||||
TORCH_CHECK(positions.size(2) == 2, "positions.shape[2] must be equal to 2");
|
||||
TORCH_CHECK(tokens.is_cuda() == positions.is_cuda(), "tokens and positions are not on the same device" );
|
||||
|
||||
if (tokens.is_cuda())
|
||||
rope_2d_cuda( tokens, positions, base, fwd );
|
||||
else
|
||||
rope_2d_cpu( tokens, positions, base, fwd );
|
||||
}
|
||||
|
||||
PYBIND11_MODULE(TORCH_EXTENSION_NAME, m) {
|
||||
m.def("rope_2d", &rope_2d, "RoPE 2d forward/backward");
|
||||
}
|
||||
@@ -0,0 +1,40 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
import torch
|
||||
|
||||
try:
|
||||
import curope as _kernels # run `python setup.py install`
|
||||
except ModuleNotFoundError:
|
||||
from . import curope as _kernels # run `python setup.py build_ext --inplace`
|
||||
|
||||
|
||||
class cuRoPE2D_func (torch.autograd.Function):
|
||||
|
||||
@staticmethod
|
||||
def forward(ctx, tokens, positions, base, F0=1):
|
||||
ctx.save_for_backward(positions)
|
||||
ctx.saved_base = base
|
||||
ctx.saved_F0 = F0
|
||||
# tokens = tokens.clone() # uncomment this if inplace doesn't work
|
||||
_kernels.rope_2d( tokens, positions, base, F0 )
|
||||
ctx.mark_dirty(tokens)
|
||||
return tokens
|
||||
|
||||
@staticmethod
|
||||
def backward(ctx, grad_res):
|
||||
positions, base, F0 = ctx.saved_tensors[0], ctx.saved_base, ctx.saved_F0
|
||||
_kernels.rope_2d( grad_res, positions, base, -F0 )
|
||||
ctx.mark_dirty(grad_res)
|
||||
return grad_res, None, None, None
|
||||
|
||||
|
||||
class cuRoPE2D(torch.nn.Module):
|
||||
def __init__(self, freq=100.0, F0=1.0):
|
||||
super().__init__()
|
||||
self.base = freq
|
||||
self.F0 = F0
|
||||
|
||||
def forward(self, tokens, positions):
|
||||
cuRoPE2D_func.apply( tokens.transpose(1,2), positions, self.base, self.F0 )
|
||||
return tokens
|
||||
@@ -0,0 +1,108 @@
|
||||
/*
|
||||
Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
*/
|
||||
|
||||
#include <torch/extension.h>
|
||||
#include <cuda.h>
|
||||
#include <cuda_runtime.h>
|
||||
#include <vector>
|
||||
|
||||
#define CHECK_CUDA(tensor) {\
|
||||
TORCH_CHECK((tensor).is_cuda(), #tensor " is not in cuda memory"); \
|
||||
TORCH_CHECK((tensor).is_contiguous(), #tensor " is not contiguous"); }
|
||||
void CHECK_KERNEL() {auto error = cudaGetLastError(); TORCH_CHECK( error == cudaSuccess, cudaGetErrorString(error));}
|
||||
|
||||
|
||||
template < typename scalar_t >
|
||||
__global__ void rope_2d_cuda_kernel(
|
||||
//scalar_t* __restrict__ tokens,
|
||||
torch::PackedTensorAccessor32<scalar_t,4,torch::RestrictPtrTraits> tokens,
|
||||
const int64_t* __restrict__ pos,
|
||||
const float base,
|
||||
const float fwd )
|
||||
// const int N, const int H, const int D )
|
||||
{
|
||||
// tokens shape = (B, N, H, D)
|
||||
const int N = tokens.size(1);
|
||||
const int H = tokens.size(2);
|
||||
const int D = tokens.size(3);
|
||||
|
||||
// each block update a single token, for all heads
|
||||
// each thread takes care of a single output
|
||||
extern __shared__ float shared[];
|
||||
float* shared_inv_freq = shared + D;
|
||||
|
||||
const int b = blockIdx.x / N;
|
||||
const int n = blockIdx.x % N;
|
||||
|
||||
const int Q = D / 4;
|
||||
// one token = [0..Q : Q..2Q : 2Q..3Q : 3Q..D]
|
||||
// u_Y v_Y u_X v_X
|
||||
|
||||
// shared memory: first, compute inv_freq
|
||||
if (threadIdx.x < Q)
|
||||
shared_inv_freq[threadIdx.x] = fwd / powf(base, threadIdx.x/float(Q));
|
||||
__syncthreads();
|
||||
|
||||
// start of X or Y part
|
||||
const int X = threadIdx.x < D/2 ? 0 : 1;
|
||||
const int m = (X*D/2) + (threadIdx.x % Q); // index of u_Y or u_X
|
||||
|
||||
// grab the cos,sin appropriate for me
|
||||
const float freq = pos[blockIdx.x*2+X] * shared_inv_freq[threadIdx.x % Q];
|
||||
const float cos = cosf(freq);
|
||||
const float sin = sinf(freq);
|
||||
/*
|
||||
float* shared_cos_sin = shared + D + D/4;
|
||||
if ((threadIdx.x % (D/2)) < Q)
|
||||
shared_cos_sin[m+0] = cosf(freq);
|
||||
else
|
||||
shared_cos_sin[m+Q] = sinf(freq);
|
||||
__syncthreads();
|
||||
const float cos = shared_cos_sin[m+0];
|
||||
const float sin = shared_cos_sin[m+Q];
|
||||
*/
|
||||
|
||||
for (int h = 0; h < H; h++)
|
||||
{
|
||||
// then, load all the token for this head in shared memory
|
||||
shared[threadIdx.x] = tokens[b][n][h][threadIdx.x];
|
||||
__syncthreads();
|
||||
|
||||
const float u = shared[m];
|
||||
const float v = shared[m+Q];
|
||||
|
||||
// write output
|
||||
if ((threadIdx.x % (D/2)) < Q)
|
||||
tokens[b][n][h][threadIdx.x] = u*cos - v*sin;
|
||||
else
|
||||
tokens[b][n][h][threadIdx.x] = v*cos + u*sin;
|
||||
}
|
||||
}
|
||||
|
||||
void rope_2d_cuda( torch::Tensor tokens, const torch::Tensor pos, const float base, const float fwd )
|
||||
{
|
||||
const int B = tokens.size(0); // batch size
|
||||
const int N = tokens.size(1); // sequence length
|
||||
const int H = tokens.size(2); // number of heads
|
||||
const int D = tokens.size(3); // dimension per head
|
||||
|
||||
TORCH_CHECK(tokens.stride(3) == 1 && tokens.stride(2) == D, "tokens are not contiguous");
|
||||
TORCH_CHECK(pos.is_contiguous(), "positions are not contiguous");
|
||||
TORCH_CHECK(pos.size(0) == B && pos.size(1) == N && pos.size(2) == 2, "bad pos.shape");
|
||||
TORCH_CHECK(D % 4 == 0, "token dim must be multiple of 4");
|
||||
|
||||
// one block for each layer, one thread per local-max
|
||||
const int THREADS_PER_BLOCK = D;
|
||||
const int N_BLOCKS = B * N; // each block takes care of H*D values
|
||||
const int SHARED_MEM = sizeof(float) * (D + D/4);
|
||||
|
||||
AT_DISPATCH_FLOATING_TYPES_AND_HALF(tokens.type(), "rope_2d_cuda", ([&] {
|
||||
rope_2d_cuda_kernel<scalar_t> <<<N_BLOCKS, THREADS_PER_BLOCK, SHARED_MEM>>> (
|
||||
//tokens.data_ptr<scalar_t>(),
|
||||
tokens.packed_accessor32<scalar_t,4,torch::RestrictPtrTraits>(),
|
||||
pos.data_ptr<int64_t>(),
|
||||
base, fwd); //, N, H, D );
|
||||
}));
|
||||
}
|
||||
@@ -0,0 +1,34 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
from setuptools import setup
|
||||
from torch import cuda
|
||||
from torch.utils.cpp_extension import BuildExtension, CUDAExtension
|
||||
|
||||
# compile for all possible CUDA architectures
|
||||
all_cuda_archs = cuda.get_gencode_flags().replace('compute=','arch=').split()
|
||||
# alternatively, you can list cuda archs that you want, eg:
|
||||
# all_cuda_archs = [
|
||||
# '-gencode', 'arch=compute_70,code=sm_70',
|
||||
# '-gencode', 'arch=compute_75,code=sm_75',
|
||||
# '-gencode', 'arch=compute_80,code=sm_80',
|
||||
# '-gencode', 'arch=compute_86,code=sm_86'
|
||||
# ]
|
||||
|
||||
setup(
|
||||
name = 'curope',
|
||||
ext_modules = [
|
||||
CUDAExtension(
|
||||
name='curope',
|
||||
sources=[
|
||||
"curope.cpp",
|
||||
"kernels.cu",
|
||||
],
|
||||
extra_compile_args = dict(
|
||||
nvcc=['-O3','--ptxas-options=-v',"--use_fast_math"]+all_cuda_archs,
|
||||
cxx=['-O3'])
|
||||
)
|
||||
],
|
||||
cmdclass = {
|
||||
'build_ext': BuildExtension
|
||||
})
|
||||
+450
@@ -0,0 +1,450 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
# --------------------------------------------------------
|
||||
# DPT head for ViTs
|
||||
# --------------------------------------------------------
|
||||
# References:
|
||||
# https://github.com/isl-org/DPT
|
||||
# https://github.com/EPFL-VILAB/MultiMAE/blob/main/multimae/output_adapters.py
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
from einops import rearrange, repeat
|
||||
from typing import Union, Tuple, Iterable, List, Optional, Dict
|
||||
|
||||
def pair(t):
|
||||
return t if isinstance(t, tuple) else (t, t)
|
||||
|
||||
def make_scratch(in_shape, out_shape, groups=1, expand=False):
|
||||
scratch = nn.Module()
|
||||
|
||||
out_shape1 = out_shape
|
||||
out_shape2 = out_shape
|
||||
out_shape3 = out_shape
|
||||
out_shape4 = out_shape
|
||||
if expand == True:
|
||||
out_shape1 = out_shape
|
||||
out_shape2 = out_shape * 2
|
||||
out_shape3 = out_shape * 4
|
||||
out_shape4 = out_shape * 8
|
||||
|
||||
scratch.layer1_rn = nn.Conv2d(
|
||||
in_shape[0],
|
||||
out_shape1,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1,
|
||||
bias=False,
|
||||
groups=groups,
|
||||
)
|
||||
scratch.layer2_rn = nn.Conv2d(
|
||||
in_shape[1],
|
||||
out_shape2,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1,
|
||||
bias=False,
|
||||
groups=groups,
|
||||
)
|
||||
scratch.layer3_rn = nn.Conv2d(
|
||||
in_shape[2],
|
||||
out_shape3,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1,
|
||||
bias=False,
|
||||
groups=groups,
|
||||
)
|
||||
scratch.layer4_rn = nn.Conv2d(
|
||||
in_shape[3],
|
||||
out_shape4,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1,
|
||||
bias=False,
|
||||
groups=groups,
|
||||
)
|
||||
|
||||
scratch.layer_rn = nn.ModuleList([
|
||||
scratch.layer1_rn,
|
||||
scratch.layer2_rn,
|
||||
scratch.layer3_rn,
|
||||
scratch.layer4_rn,
|
||||
])
|
||||
|
||||
return scratch
|
||||
|
||||
class ResidualConvUnit_custom(nn.Module):
|
||||
"""Residual convolution module."""
|
||||
|
||||
def __init__(self, features, activation, bn):
|
||||
"""Init.
|
||||
Args:
|
||||
features (int): number of features
|
||||
"""
|
||||
super().__init__()
|
||||
|
||||
self.bn = bn
|
||||
|
||||
self.groups = 1
|
||||
|
||||
self.conv1 = nn.Conv2d(
|
||||
features,
|
||||
features,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1,
|
||||
bias=not self.bn,
|
||||
groups=self.groups,
|
||||
)
|
||||
|
||||
self.conv2 = nn.Conv2d(
|
||||
features,
|
||||
features,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1,
|
||||
bias=not self.bn,
|
||||
groups=self.groups,
|
||||
)
|
||||
|
||||
if self.bn == True:
|
||||
self.bn1 = nn.BatchNorm2d(features)
|
||||
self.bn2 = nn.BatchNorm2d(features)
|
||||
|
||||
self.activation = activation
|
||||
|
||||
self.skip_add = nn.quantized.FloatFunctional()
|
||||
|
||||
def forward(self, x):
|
||||
"""Forward pass.
|
||||
Args:
|
||||
x (tensor): input
|
||||
Returns:
|
||||
tensor: output
|
||||
"""
|
||||
|
||||
out = self.activation(x)
|
||||
out = self.conv1(out)
|
||||
if self.bn == True:
|
||||
out = self.bn1(out)
|
||||
|
||||
out = self.activation(out)
|
||||
out = self.conv2(out)
|
||||
if self.bn == True:
|
||||
out = self.bn2(out)
|
||||
|
||||
if self.groups > 1:
|
||||
out = self.conv_merge(out)
|
||||
|
||||
return self.skip_add.add(out, x)
|
||||
|
||||
class FeatureFusionBlock_custom(nn.Module):
|
||||
"""Feature fusion block."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
features,
|
||||
activation,
|
||||
deconv=False,
|
||||
bn=False,
|
||||
expand=False,
|
||||
align_corners=True,
|
||||
width_ratio=1,
|
||||
):
|
||||
"""Init.
|
||||
Args:
|
||||
features (int): number of features
|
||||
"""
|
||||
super(FeatureFusionBlock_custom, self).__init__()
|
||||
self.width_ratio = width_ratio
|
||||
|
||||
self.deconv = deconv
|
||||
self.align_corners = align_corners
|
||||
|
||||
self.groups = 1
|
||||
|
||||
self.expand = expand
|
||||
out_features = features
|
||||
if self.expand == True:
|
||||
out_features = features // 2
|
||||
|
||||
self.out_conv = nn.Conv2d(
|
||||
features,
|
||||
out_features,
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0,
|
||||
bias=True,
|
||||
groups=1,
|
||||
)
|
||||
|
||||
self.resConfUnit1 = ResidualConvUnit_custom(features, activation, bn)
|
||||
self.resConfUnit2 = ResidualConvUnit_custom(features, activation, bn)
|
||||
|
||||
self.skip_add = nn.quantized.FloatFunctional()
|
||||
|
||||
def forward(self, *xs):
|
||||
"""Forward pass.
|
||||
Returns:
|
||||
tensor: output
|
||||
"""
|
||||
output = xs[0]
|
||||
|
||||
if len(xs) == 2:
|
||||
res = self.resConfUnit1(xs[1])
|
||||
if self.width_ratio != 1:
|
||||
res = F.interpolate(res, size=(output.shape[2], output.shape[3]), mode='bilinear')
|
||||
|
||||
output = self.skip_add.add(output, res)
|
||||
# output += res
|
||||
|
||||
output = self.resConfUnit2(output)
|
||||
|
||||
if self.width_ratio != 1:
|
||||
# and output.shape[3] < self.width_ratio * output.shape[2]
|
||||
#size=(image.shape[])
|
||||
if (output.shape[3] / output.shape[2]) < (2 / 3) * self.width_ratio:
|
||||
shape = 3 * output.shape[3]
|
||||
else:
|
||||
shape = int(self.width_ratio * 2 * output.shape[2])
|
||||
output = F.interpolate(output, size=(2* output.shape[2], shape), mode='bilinear')
|
||||
else:
|
||||
output = nn.functional.interpolate(output, scale_factor=2,
|
||||
mode="bilinear", align_corners=self.align_corners)
|
||||
output = self.out_conv(output)
|
||||
return output
|
||||
|
||||
def make_fusion_block(features, use_bn, width_ratio=1):
|
||||
return FeatureFusionBlock_custom(
|
||||
features,
|
||||
nn.ReLU(False),
|
||||
deconv=False,
|
||||
bn=use_bn,
|
||||
expand=False,
|
||||
align_corners=True,
|
||||
width_ratio=width_ratio,
|
||||
)
|
||||
|
||||
class Interpolate(nn.Module):
|
||||
"""Interpolation module."""
|
||||
|
||||
def __init__(self, scale_factor, mode, align_corners=False):
|
||||
"""Init.
|
||||
Args:
|
||||
scale_factor (float): scaling
|
||||
mode (str): interpolation mode
|
||||
"""
|
||||
super(Interpolate, self).__init__()
|
||||
|
||||
self.interp = nn.functional.interpolate
|
||||
self.scale_factor = scale_factor
|
||||
self.mode = mode
|
||||
self.align_corners = align_corners
|
||||
|
||||
def forward(self, x):
|
||||
"""Forward pass.
|
||||
Args:
|
||||
x (tensor): input
|
||||
Returns:
|
||||
tensor: interpolated data
|
||||
"""
|
||||
|
||||
x = self.interp(
|
||||
x,
|
||||
scale_factor=self.scale_factor,
|
||||
mode=self.mode,
|
||||
align_corners=self.align_corners,
|
||||
)
|
||||
|
||||
return x
|
||||
|
||||
class DPTOutputAdapter(nn.Module):
|
||||
"""DPT output adapter.
|
||||
|
||||
:param num_cahnnels: Number of output channels
|
||||
:param stride_level: tride level compared to the full-sized image.
|
||||
E.g. 4 for 1/4th the size of the image.
|
||||
:param patch_size_full: Int or tuple of the patch size over the full image size.
|
||||
Patch size for smaller inputs will be computed accordingly.
|
||||
:param hooks: Index of intermediate layers
|
||||
:param layer_dims: Dimension of intermediate layers
|
||||
:param feature_dim: Feature dimension
|
||||
:param last_dim: out_channels/in_channels for the last two Conv2d when head_type == regression
|
||||
:param use_bn: If set to True, activates batch norm
|
||||
:param dim_tokens_enc: Dimension of tokens coming from encoder
|
||||
"""
|
||||
|
||||
def __init__(self,
|
||||
num_channels: int = 1,
|
||||
stride_level: int = 1,
|
||||
patch_size: Union[int, Tuple[int, int]] = 16,
|
||||
main_tasks: Iterable[str] = ('rgb',),
|
||||
hooks: List[int] = [2, 5, 8, 11],
|
||||
layer_dims: List[int] = [96, 192, 384, 768],
|
||||
feature_dim: int = 256,
|
||||
last_dim: int = 32,
|
||||
use_bn: bool = False,
|
||||
dim_tokens_enc: Optional[int] = None,
|
||||
head_type: str = 'regression',
|
||||
output_width_ratio=1,
|
||||
**kwargs):
|
||||
super().__init__()
|
||||
self.num_channels = num_channels
|
||||
self.stride_level = stride_level
|
||||
self.patch_size = pair(patch_size)
|
||||
self.main_tasks = main_tasks
|
||||
self.hooks = hooks
|
||||
self.layer_dims = layer_dims
|
||||
self.feature_dim = feature_dim
|
||||
self.dim_tokens_enc = dim_tokens_enc * len(self.main_tasks) if dim_tokens_enc is not None else None
|
||||
self.head_type = head_type
|
||||
|
||||
# Actual patch height and width, taking into account stride of input
|
||||
self.P_H = max(1, self.patch_size[0] // stride_level)
|
||||
self.P_W = max(1, self.patch_size[1] // stride_level)
|
||||
|
||||
self.scratch = make_scratch(layer_dims, feature_dim, groups=1, expand=False)
|
||||
|
||||
self.scratch.refinenet1 = make_fusion_block(feature_dim, use_bn, output_width_ratio)
|
||||
self.scratch.refinenet2 = make_fusion_block(feature_dim, use_bn, output_width_ratio)
|
||||
self.scratch.refinenet3 = make_fusion_block(feature_dim, use_bn, output_width_ratio)
|
||||
self.scratch.refinenet4 = make_fusion_block(feature_dim, use_bn, output_width_ratio)
|
||||
|
||||
if self.head_type == 'regression':
|
||||
# The "DPTDepthModel" head
|
||||
self.head = nn.Sequential(
|
||||
nn.Conv2d(feature_dim, feature_dim // 2, kernel_size=3, stride=1, padding=1),
|
||||
Interpolate(scale_factor=2, mode="bilinear", align_corners=True),
|
||||
nn.Conv2d(feature_dim // 2, last_dim, kernel_size=3, stride=1, padding=1),
|
||||
nn.ReLU(True),
|
||||
nn.Conv2d(last_dim, self.num_channels, kernel_size=1, stride=1, padding=0)
|
||||
)
|
||||
elif self.head_type == 'semseg':
|
||||
# The "DPTSegmentationModel" head
|
||||
self.head = nn.Sequential(
|
||||
nn.Conv2d(feature_dim, feature_dim, kernel_size=3, padding=1, bias=False),
|
||||
nn.BatchNorm2d(feature_dim) if use_bn else nn.Identity(),
|
||||
nn.ReLU(True),
|
||||
nn.Dropout(0.1, False),
|
||||
nn.Conv2d(feature_dim, self.num_channels, kernel_size=1),
|
||||
Interpolate(scale_factor=2, mode="bilinear", align_corners=True),
|
||||
)
|
||||
else:
|
||||
raise ValueError('DPT head_type must be "regression" or "semseg".')
|
||||
|
||||
if self.dim_tokens_enc is not None:
|
||||
self.init(dim_tokens_enc=dim_tokens_enc)
|
||||
|
||||
def init(self, dim_tokens_enc=768):
|
||||
"""
|
||||
Initialize parts of decoder that are dependent on dimension of encoder tokens.
|
||||
Should be called when setting up MultiMAE.
|
||||
|
||||
:param dim_tokens_enc: Dimension of tokens coming from encoder
|
||||
"""
|
||||
#print(dim_tokens_enc)
|
||||
|
||||
# Set up activation postprocessing layers
|
||||
if isinstance(dim_tokens_enc, int):
|
||||
dim_tokens_enc = 4 * [dim_tokens_enc]
|
||||
|
||||
self.dim_tokens_enc = [dt * len(self.main_tasks) for dt in dim_tokens_enc]
|
||||
|
||||
self.act_1_postprocess = nn.Sequential(
|
||||
nn.Conv2d(
|
||||
in_channels=self.dim_tokens_enc[0],
|
||||
out_channels=self.layer_dims[0],
|
||||
kernel_size=1, stride=1, padding=0,
|
||||
),
|
||||
nn.ConvTranspose2d(
|
||||
in_channels=self.layer_dims[0],
|
||||
out_channels=self.layer_dims[0],
|
||||
kernel_size=4, stride=4, padding=0,
|
||||
bias=True, dilation=1, groups=1,
|
||||
)
|
||||
)
|
||||
|
||||
self.act_2_postprocess = nn.Sequential(
|
||||
nn.Conv2d(
|
||||
in_channels=self.dim_tokens_enc[1],
|
||||
out_channels=self.layer_dims[1],
|
||||
kernel_size=1, stride=1, padding=0,
|
||||
),
|
||||
nn.ConvTranspose2d(
|
||||
in_channels=self.layer_dims[1],
|
||||
out_channels=self.layer_dims[1],
|
||||
kernel_size=2, stride=2, padding=0,
|
||||
bias=True, dilation=1, groups=1,
|
||||
)
|
||||
)
|
||||
|
||||
self.act_3_postprocess = nn.Sequential(
|
||||
nn.Conv2d(
|
||||
in_channels=self.dim_tokens_enc[2],
|
||||
out_channels=self.layer_dims[2],
|
||||
kernel_size=1, stride=1, padding=0,
|
||||
)
|
||||
)
|
||||
|
||||
self.act_4_postprocess = nn.Sequential(
|
||||
nn.Conv2d(
|
||||
in_channels=self.dim_tokens_enc[3],
|
||||
out_channels=self.layer_dims[3],
|
||||
kernel_size=1, stride=1, padding=0,
|
||||
),
|
||||
nn.Conv2d(
|
||||
in_channels=self.layer_dims[3],
|
||||
out_channels=self.layer_dims[3],
|
||||
kernel_size=3, stride=2, padding=1,
|
||||
)
|
||||
)
|
||||
|
||||
self.act_postprocess = nn.ModuleList([
|
||||
self.act_1_postprocess,
|
||||
self.act_2_postprocess,
|
||||
self.act_3_postprocess,
|
||||
self.act_4_postprocess
|
||||
])
|
||||
|
||||
def adapt_tokens(self, encoder_tokens):
|
||||
# Adapt tokens
|
||||
x = []
|
||||
x.append(encoder_tokens[:, :])
|
||||
x = torch.cat(x, dim=-1)
|
||||
return x
|
||||
|
||||
def forward(self, encoder_tokens: List[torch.Tensor], image_size):
|
||||
#input_info: Dict):
|
||||
assert self.dim_tokens_enc is not None, 'Need to call init(dim_tokens_enc) function first'
|
||||
H, W = image_size
|
||||
|
||||
# Number of patches in height and width
|
||||
N_H = H // (self.stride_level * self.P_H)
|
||||
N_W = W // (self.stride_level * self.P_W)
|
||||
|
||||
# Hook decoder onto 4 layers from specified ViT layers
|
||||
layers = [encoder_tokens[hook] for hook in self.hooks]
|
||||
|
||||
# Extract only task-relevant tokens and ignore global tokens.
|
||||
layers = [self.adapt_tokens(l) for l in layers]
|
||||
|
||||
# Reshape tokens to spatial representation
|
||||
layers = [rearrange(l, 'b (nh nw) c -> b c nh nw', nh=N_H, nw=N_W) for l in layers]
|
||||
|
||||
layers = [self.act_postprocess[idx](l) for idx, l in enumerate(layers)]
|
||||
# Project layers to chosen feature dim
|
||||
layers = [self.scratch.layer_rn[idx](l) for idx, l in enumerate(layers)]
|
||||
|
||||
# Fuse layers using refinement stages
|
||||
path_4 = self.scratch.refinenet4(layers[3])
|
||||
path_3 = self.scratch.refinenet3(path_4, layers[2])
|
||||
path_2 = self.scratch.refinenet2(path_3, layers[1])
|
||||
path_1 = self.scratch.refinenet1(path_2, layers[0])
|
||||
|
||||
# Output head
|
||||
out = self.head(path_1)
|
||||
|
||||
return out
|
||||
@@ -0,0 +1,58 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
# --------------------------------------------------------
|
||||
# Heads for downstream tasks
|
||||
# --------------------------------------------------------
|
||||
|
||||
"""
|
||||
A head is a module where the __init__ defines only the head hyperparameters.
|
||||
A method setup(croconet) takes a CroCoNet and set all layers according to the head and croconet attributes.
|
||||
The forward takes the features as well as a dictionary img_info containing the keys 'width' and 'height'
|
||||
"""
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from .dpt_block import DPTOutputAdapter
|
||||
|
||||
|
||||
class PixelwiseTaskWithDPT(nn.Module):
|
||||
""" DPT module for CroCo.
|
||||
by default, hooks_idx will be equal to:
|
||||
* for encoder-only: 4 equally spread layers
|
||||
* for encoder+decoder: last encoder + 3 equally spread layers of the decoder
|
||||
"""
|
||||
|
||||
def __init__(self, *, hooks_idx=None, layer_dims=[96,192,384,768],
|
||||
output_width_ratio=1, num_channels=1, postprocess=None, **kwargs):
|
||||
super(PixelwiseTaskWithDPT, self).__init__()
|
||||
self.return_all_blocks = True # backbone needs to return all layers
|
||||
self.postprocess = postprocess
|
||||
self.output_width_ratio = output_width_ratio
|
||||
self.num_channels = num_channels
|
||||
self.hooks_idx = hooks_idx
|
||||
self.layer_dims = layer_dims
|
||||
|
||||
def setup(self, croconet):
|
||||
dpt_args = {'output_width_ratio': self.output_width_ratio, 'num_channels': self.num_channels}
|
||||
if self.hooks_idx is None:
|
||||
if hasattr(croconet, 'dec_blocks'): # encoder + decoder
|
||||
step = {8: 3, 12: 4, 24: 8}[croconet.dec_depth]
|
||||
hooks_idx = [croconet.dec_depth+croconet.enc_depth-1-i*step for i in range(3,-1,-1)]
|
||||
else: # encoder only
|
||||
step = croconet.enc_depth//4
|
||||
hooks_idx = [croconet.enc_depth-1-i*step for i in range(3,-1,-1)]
|
||||
self.hooks_idx = hooks_idx
|
||||
print(f' PixelwiseTaskWithDPT: automatically setting hook_idxs={self.hooks_idx}')
|
||||
dpt_args['hooks'] = self.hooks_idx
|
||||
dpt_args['layer_dims'] = self.layer_dims
|
||||
self.dpt = DPTOutputAdapter(**dpt_args)
|
||||
dim_tokens = [croconet.enc_embed_dim if hook<croconet.enc_depth else croconet.dec_embed_dim for hook in self.hooks_idx]
|
||||
dpt_init_args = {'dim_tokens_enc': dim_tokens}
|
||||
self.dpt.init(**dpt_init_args)
|
||||
|
||||
|
||||
def forward(self, x, img_info):
|
||||
out = self.dpt(x, image_size=(img_info['height'],img_info['width']))
|
||||
if self.postprocess: out = self.postprocess(out)
|
||||
return out
|
||||
@@ -0,0 +1,25 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
|
||||
# --------------------------------------------------------
|
||||
# Masking utils
|
||||
# --------------------------------------------------------
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
|
||||
class RandomMask(nn.Module):
|
||||
"""
|
||||
random masking
|
||||
"""
|
||||
|
||||
def __init__(self, num_patches, mask_ratio):
|
||||
super().__init__()
|
||||
self.num_patches = num_patches
|
||||
self.num_mask = int(mask_ratio * self.num_patches)
|
||||
|
||||
def __call__(self, x):
|
||||
noise = torch.rand(x.size(0), self.num_patches, device=x.device)
|
||||
argsort = torch.argsort(noise, dim=1)
|
||||
return argsort < self.num_mask
|
||||
+159
@@ -0,0 +1,159 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
|
||||
# --------------------------------------------------------
|
||||
# Position embedding utils
|
||||
# --------------------------------------------------------
|
||||
|
||||
|
||||
|
||||
import numpy as np
|
||||
|
||||
import torch
|
||||
|
||||
# --------------------------------------------------------
|
||||
# 2D sine-cosine position embedding
|
||||
# References:
|
||||
# MAE: https://github.com/facebookresearch/mae/blob/main/util/pos_embed.py
|
||||
# Transformer: https://github.com/tensorflow/models/blob/master/official/nlp/transformer/model_utils.py
|
||||
# MoCo v3: https://github.com/facebookresearch/moco-v3
|
||||
# --------------------------------------------------------
|
||||
def get_2d_sincos_pos_embed(embed_dim, grid_size, n_cls_token=0):
|
||||
"""
|
||||
grid_size: int of the grid height and width
|
||||
return:
|
||||
pos_embed: [grid_size*grid_size, embed_dim] or [n_cls_token+grid_size*grid_size, embed_dim] (w/ or w/o cls_token)
|
||||
"""
|
||||
grid_h = np.arange(grid_size, dtype=np.float32)
|
||||
grid_w = np.arange(grid_size, dtype=np.float32)
|
||||
grid = np.meshgrid(grid_w, grid_h) # here w goes first
|
||||
grid = np.stack(grid, axis=0)
|
||||
|
||||
grid = grid.reshape([2, 1, grid_size, grid_size])
|
||||
pos_embed = get_2d_sincos_pos_embed_from_grid(embed_dim, grid)
|
||||
if n_cls_token>0:
|
||||
pos_embed = np.concatenate([np.zeros([n_cls_token, embed_dim]), pos_embed], axis=0)
|
||||
return pos_embed
|
||||
|
||||
|
||||
def get_2d_sincos_pos_embed_from_grid(embed_dim, grid):
|
||||
assert embed_dim % 2 == 0
|
||||
|
||||
# use half of dimensions to encode grid_h
|
||||
emb_h = get_1d_sincos_pos_embed_from_grid(embed_dim // 2, grid[0]) # (H*W, D/2)
|
||||
emb_w = get_1d_sincos_pos_embed_from_grid(embed_dim // 2, grid[1]) # (H*W, D/2)
|
||||
|
||||
emb = np.concatenate([emb_h, emb_w], axis=1) # (H*W, D)
|
||||
return emb
|
||||
|
||||
|
||||
def get_1d_sincos_pos_embed_from_grid(embed_dim, pos):
|
||||
"""
|
||||
embed_dim: output dimension for each position
|
||||
pos: a list of positions to be encoded: size (M,)
|
||||
out: (M, D)
|
||||
"""
|
||||
assert embed_dim % 2 == 0
|
||||
omega = np.arange(embed_dim // 2, dtype=float)
|
||||
omega /= embed_dim / 2.
|
||||
omega = 1. / 10000**omega # (D/2,)
|
||||
|
||||
pos = pos.reshape(-1) # (M,)
|
||||
out = np.einsum('m,d->md', pos, omega) # (M, D/2), outer product
|
||||
|
||||
emb_sin = np.sin(out) # (M, D/2)
|
||||
emb_cos = np.cos(out) # (M, D/2)
|
||||
|
||||
emb = np.concatenate([emb_sin, emb_cos], axis=1) # (M, D)
|
||||
return emb
|
||||
|
||||
|
||||
# --------------------------------------------------------
|
||||
# Interpolate position embeddings for high-resolution
|
||||
# References:
|
||||
# MAE: https://github.com/facebookresearch/mae/blob/main/util/pos_embed.py
|
||||
# DeiT: https://github.com/facebookresearch/deit
|
||||
# --------------------------------------------------------
|
||||
def interpolate_pos_embed(model, checkpoint_model):
|
||||
if 'pos_embed' in checkpoint_model:
|
||||
pos_embed_checkpoint = checkpoint_model['pos_embed']
|
||||
embedding_size = pos_embed_checkpoint.shape[-1]
|
||||
num_patches = model.patch_embed.num_patches
|
||||
num_extra_tokens = model.pos_embed.shape[-2] - num_patches
|
||||
# height (== width) for the checkpoint position embedding
|
||||
orig_size = int((pos_embed_checkpoint.shape[-2] - num_extra_tokens) ** 0.5)
|
||||
# height (== width) for the new position embedding
|
||||
new_size = int(num_patches ** 0.5)
|
||||
# class_token and dist_token are kept unchanged
|
||||
if orig_size != new_size:
|
||||
print("Position interpolate from %dx%d to %dx%d" % (orig_size, orig_size, new_size, new_size))
|
||||
extra_tokens = pos_embed_checkpoint[:, :num_extra_tokens]
|
||||
# only the position tokens are interpolated
|
||||
pos_tokens = pos_embed_checkpoint[:, num_extra_tokens:]
|
||||
pos_tokens = pos_tokens.reshape(-1, orig_size, orig_size, embedding_size).permute(0, 3, 1, 2)
|
||||
pos_tokens = torch.nn.functional.interpolate(
|
||||
pos_tokens, size=(new_size, new_size), mode='bicubic', align_corners=False)
|
||||
pos_tokens = pos_tokens.permute(0, 2, 3, 1).flatten(1, 2)
|
||||
new_pos_embed = torch.cat((extra_tokens, pos_tokens), dim=1)
|
||||
checkpoint_model['pos_embed'] = new_pos_embed
|
||||
|
||||
|
||||
#----------------------------------------------------------
|
||||
# RoPE2D: RoPE implementation in 2D
|
||||
#----------------------------------------------------------
|
||||
|
||||
try:
|
||||
from models.curope import cuRoPE2D
|
||||
RoPE2D = cuRoPE2D
|
||||
except ImportError:
|
||||
print('Warning, cannot find cuda-compiled version of RoPE2D, using a slow pytorch version instead')
|
||||
|
||||
class RoPE2D(torch.nn.Module):
|
||||
|
||||
def __init__(self, freq=100.0, F0=1.0):
|
||||
super().__init__()
|
||||
self.base = freq
|
||||
self.F0 = F0
|
||||
self.cache = {}
|
||||
|
||||
def get_cos_sin(self, D, seq_len, device, dtype):
|
||||
if (D,seq_len,device,dtype) not in self.cache:
|
||||
inv_freq = 1.0 / (self.base ** (torch.arange(0, D, 2).float().to(device) / D))
|
||||
t = torch.arange(seq_len, device=device, dtype=inv_freq.dtype)
|
||||
freqs = torch.einsum("i,j->ij", t, inv_freq).to(dtype)
|
||||
freqs = torch.cat((freqs, freqs), dim=-1)
|
||||
cos = freqs.cos() # (Seq, Dim)
|
||||
sin = freqs.sin()
|
||||
self.cache[D,seq_len,device,dtype] = (cos,sin)
|
||||
return self.cache[D,seq_len,device,dtype]
|
||||
|
||||
@staticmethod
|
||||
def rotate_half(x):
|
||||
x1, x2 = x[..., : x.shape[-1] // 2], x[..., x.shape[-1] // 2 :]
|
||||
return torch.cat((-x2, x1), dim=-1)
|
||||
|
||||
def apply_rope1d(self, tokens, pos1d, cos, sin):
|
||||
assert pos1d.ndim==2
|
||||
cos = torch.nn.functional.embedding(pos1d, cos)[:, None, :, :]
|
||||
sin = torch.nn.functional.embedding(pos1d, sin)[:, None, :, :]
|
||||
return (tokens * cos) + (self.rotate_half(tokens) * sin)
|
||||
|
||||
def forward(self, tokens, positions):
|
||||
"""
|
||||
input:
|
||||
* tokens: batch_size x nheads x ntokens x dim
|
||||
* positions: batch_size x ntokens x 2 (y and x position of each token)
|
||||
output:
|
||||
* tokens after appplying RoPE2D (batch_size x nheads x ntokens x dim)
|
||||
"""
|
||||
assert tokens.size(3)%2==0, "number of dimensions should be a multiple of two"
|
||||
D = tokens.size(3) // 2
|
||||
assert positions.ndim==3 and positions.shape[-1] == 2 # Batch, Seq, 2
|
||||
cos, sin = self.get_cos_sin(D, int(positions.max())+1, tokens.device, tokens.dtype)
|
||||
# split features into two along the feature dimension, and apply rope1d on each half
|
||||
y, x = tokens.chunk(2, dim=-1)
|
||||
y = self.apply_rope1d(y, positions[:,:,0], cos, sin)
|
||||
x = self.apply_rope1d(x, positions[:,:,1], cos, sin)
|
||||
tokens = torch.cat((y, x), dim=-1)
|
||||
return tokens
|
||||
+254
@@ -0,0 +1,254 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# Pre-training CroCo
|
||||
# --------------------------------------------------------
|
||||
# References:
|
||||
# MAE: https://github.com/facebookresearch/mae
|
||||
# DeiT: https://github.com/facebookresearch/deit
|
||||
# BEiT: https://github.com/microsoft/unilm/tree/master/beit
|
||||
# --------------------------------------------------------
|
||||
import argparse
|
||||
import datetime
|
||||
import json
|
||||
import numpy as np
|
||||
import os
|
||||
import sys
|
||||
import time
|
||||
import math
|
||||
from pathlib import Path
|
||||
from typing import Iterable
|
||||
|
||||
import torch
|
||||
import torch.distributed as dist
|
||||
import torch.backends.cudnn as cudnn
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
import torchvision.transforms as transforms
|
||||
import torchvision.datasets as datasets
|
||||
|
||||
import utils.misc as misc
|
||||
from utils.misc import NativeScalerWithGradNormCount as NativeScaler
|
||||
from models.croco import CroCoNet
|
||||
from models.criterion import MaskedMSE
|
||||
from datasets.pairs_dataset import PairsDataset
|
||||
|
||||
|
||||
def get_args_parser():
|
||||
parser = argparse.ArgumentParser('CroCo pre-training', add_help=False)
|
||||
# model and criterion
|
||||
parser.add_argument('--model', default='CroCoNet()', type=str, help="string containing the model to build")
|
||||
parser.add_argument('--norm_pix_loss', default=1, choices=[0,1], help="apply per-patch mean/std normalization before applying the loss")
|
||||
# dataset
|
||||
parser.add_argument('--dataset', default='habitat_release', type=str, help="training set")
|
||||
parser.add_argument('--transforms', default='crop224+acolor', type=str, help="transforms to apply") # in the paper, we also use some homography and rotation, but find later that they were not useful or even harmful
|
||||
# training
|
||||
parser.add_argument('--seed', default=0, type=int, help="Random seed")
|
||||
parser.add_argument('--batch_size', default=64, type=int, help="Batch size per GPU (effective batch size is batch_size * accum_iter * # gpus")
|
||||
parser.add_argument('--epochs', default=800, type=int, help="Maximum number of epochs for the scheduler")
|
||||
parser.add_argument('--max_epoch', default=400, type=int, help="Stop training at this epoch")
|
||||
parser.add_argument('--accum_iter', default=1, type=int, help="Accumulate gradient iterations (for increasing the effective batch size under memory constraints)")
|
||||
parser.add_argument('--weight_decay', type=float, default=0.05, help="weight decay (default: 0.05)")
|
||||
parser.add_argument('--lr', type=float, default=None, metavar='LR', help='learning rate (absolute lr)')
|
||||
parser.add_argument('--blr', type=float, default=1.5e-4, metavar='LR', help='base learning rate: absolute_lr = base_lr * total_batch_size / 256')
|
||||
parser.add_argument('--min_lr', type=float, default=0., metavar='LR', help='lower lr bound for cyclic schedulers that hit 0')
|
||||
parser.add_argument('--warmup_epochs', type=int, default=40, metavar='N', help='epochs to warmup LR')
|
||||
parser.add_argument('--amp', type=int, default=1, choices=[0,1], help="Use Automatic Mixed Precision for pretraining")
|
||||
# others
|
||||
parser.add_argument('--num_workers', default=8, type=int)
|
||||
parser.add_argument('--world_size', default=1, type=int, help='number of distributed processes')
|
||||
parser.add_argument('--local_rank', default=-1, type=int)
|
||||
parser.add_argument('--dist_url', default='env://', help='url used to set up distributed training')
|
||||
parser.add_argument('--save_freq', default=1, type=int, help='frequence (number of epochs) to save checkpoint in checkpoint-last.pth')
|
||||
parser.add_argument('--keep_freq', default=20, type=int, help='frequence (number of epochs) to save checkpoint in checkpoint-%d.pth')
|
||||
parser.add_argument('--print_freq', default=20, type=int, help='frequence (number of iterations) to print infos while training')
|
||||
# paths
|
||||
parser.add_argument('--output_dir', default='./output/', type=str, help="path where to save the output")
|
||||
parser.add_argument('--data_dir', default='./data/', type=str, help="path where data are stored")
|
||||
return parser
|
||||
|
||||
|
||||
|
||||
|
||||
def main(args):
|
||||
misc.init_distributed_mode(args)
|
||||
global_rank = misc.get_rank()
|
||||
world_size = misc.get_world_size()
|
||||
|
||||
print("output_dir: "+args.output_dir)
|
||||
if args.output_dir:
|
||||
Path(args.output_dir).mkdir(parents=True, exist_ok=True)
|
||||
|
||||
# auto resume
|
||||
last_ckpt_fname = os.path.join(args.output_dir, f'checkpoint-last.pth')
|
||||
args.resume = last_ckpt_fname if os.path.isfile(last_ckpt_fname) else None
|
||||
|
||||
print('job dir: {}'.format(os.path.dirname(os.path.realpath(__file__))))
|
||||
print("{}".format(args).replace(', ', ',\n'))
|
||||
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
device = torch.device(device)
|
||||
|
||||
# fix the seed
|
||||
seed = args.seed + misc.get_rank()
|
||||
torch.manual_seed(seed)
|
||||
np.random.seed(seed)
|
||||
|
||||
cudnn.benchmark = True
|
||||
|
||||
## training dataset and loader
|
||||
print('Building dataset for {:s} with transforms {:s}'.format(args.dataset, args.transforms))
|
||||
dataset = PairsDataset(args.dataset, trfs=args.transforms, data_dir=args.data_dir)
|
||||
if world_size>1:
|
||||
sampler_train = torch.utils.data.DistributedSampler(
|
||||
dataset, num_replicas=world_size, rank=global_rank, shuffle=True
|
||||
)
|
||||
print("Sampler_train = %s" % str(sampler_train))
|
||||
else:
|
||||
sampler_train = torch.utils.data.RandomSampler(dataset)
|
||||
data_loader_train = torch.utils.data.DataLoader(
|
||||
dataset, sampler=sampler_train,
|
||||
batch_size=args.batch_size,
|
||||
num_workers=args.num_workers,
|
||||
pin_memory=True,
|
||||
drop_last=True,
|
||||
)
|
||||
|
||||
## model
|
||||
print('Loading model: {:s}'.format(args.model))
|
||||
model = eval(args.model)
|
||||
print('Loading criterion: MaskedMSE(norm_pix_loss={:s})'.format(str(bool(args.norm_pix_loss))))
|
||||
criterion = MaskedMSE(norm_pix_loss=bool(args.norm_pix_loss))
|
||||
|
||||
model.to(device)
|
||||
model_without_ddp = model
|
||||
print("Model = %s" % str(model_without_ddp))
|
||||
|
||||
eff_batch_size = args.batch_size * args.accum_iter * misc.get_world_size()
|
||||
if args.lr is None: # only base_lr is specified
|
||||
args.lr = args.blr * eff_batch_size / 256
|
||||
print("base lr: %.2e" % (args.lr * 256 / eff_batch_size))
|
||||
print("actual lr: %.2e" % args.lr)
|
||||
print("accumulate grad iterations: %d" % args.accum_iter)
|
||||
print("effective batch size: %d" % eff_batch_size)
|
||||
|
||||
if args.distributed:
|
||||
model = torch.nn.parallel.DistributedDataParallel(model, device_ids=[args.gpu], find_unused_parameters=True, static_graph=True)
|
||||
model_without_ddp = model.module
|
||||
|
||||
param_groups = misc.get_parameter_groups(model_without_ddp, args.weight_decay) # following timm: set wd as 0 for bias and norm layers
|
||||
optimizer = torch.optim.AdamW(param_groups, lr=args.lr, betas=(0.9, 0.95))
|
||||
print(optimizer)
|
||||
loss_scaler = NativeScaler()
|
||||
|
||||
misc.load_model(args=args, model_without_ddp=model_without_ddp, optimizer=optimizer, loss_scaler=loss_scaler)
|
||||
|
||||
if global_rank == 0 and args.output_dir is not None:
|
||||
log_writer = SummaryWriter(log_dir=args.output_dir)
|
||||
else:
|
||||
log_writer = None
|
||||
|
||||
print(f"Start training until {args.max_epoch} epochs")
|
||||
start_time = time.time()
|
||||
for epoch in range(args.start_epoch, args.max_epoch):
|
||||
if world_size>1:
|
||||
data_loader_train.sampler.set_epoch(epoch)
|
||||
|
||||
train_stats = train_one_epoch(
|
||||
model, criterion, data_loader_train,
|
||||
optimizer, device, epoch, loss_scaler,
|
||||
log_writer=log_writer,
|
||||
args=args
|
||||
)
|
||||
|
||||
if args.output_dir and epoch % args.save_freq == 0 :
|
||||
misc.save_model(
|
||||
args=args, model_without_ddp=model_without_ddp, optimizer=optimizer,
|
||||
loss_scaler=loss_scaler, epoch=epoch, fname='last')
|
||||
|
||||
if args.output_dir and (epoch % args.keep_freq == 0 or epoch + 1 == args.max_epoch) and (epoch>0 or args.max_epoch==1):
|
||||
misc.save_model(
|
||||
args=args, model_without_ddp=model_without_ddp, optimizer=optimizer,
|
||||
loss_scaler=loss_scaler, epoch=epoch)
|
||||
|
||||
log_stats = {**{f'train_{k}': v for k, v in train_stats.items()},
|
||||
'epoch': epoch,}
|
||||
|
||||
if args.output_dir and misc.is_main_process():
|
||||
if log_writer is not None:
|
||||
log_writer.flush()
|
||||
with open(os.path.join(args.output_dir, "log.txt"), mode="a", encoding="utf-8") as f:
|
||||
f.write(json.dumps(log_stats) + "\n")
|
||||
|
||||
total_time = time.time() - start_time
|
||||
total_time_str = str(datetime.timedelta(seconds=int(total_time)))
|
||||
print('Training time {}'.format(total_time_str))
|
||||
|
||||
|
||||
|
||||
|
||||
def train_one_epoch(model: torch.nn.Module, criterion: torch.nn.Module,
|
||||
data_loader: Iterable, optimizer: torch.optim.Optimizer,
|
||||
device: torch.device, epoch: int, loss_scaler,
|
||||
log_writer=None,
|
||||
args=None):
|
||||
model.train(True)
|
||||
metric_logger = misc.MetricLogger(delimiter=" ")
|
||||
metric_logger.add_meter('lr', misc.SmoothedValue(window_size=1, fmt='{value:.6f}'))
|
||||
header = 'Epoch: [{}]'.format(epoch)
|
||||
accum_iter = args.accum_iter
|
||||
|
||||
optimizer.zero_grad()
|
||||
|
||||
if log_writer is not None:
|
||||
print('log_dir: {}'.format(log_writer.log_dir))
|
||||
|
||||
for data_iter_step, (image1, image2) in enumerate(metric_logger.log_every(data_loader, args.print_freq, header)):
|
||||
|
||||
# we use a per iteration lr scheduler
|
||||
if data_iter_step % accum_iter == 0:
|
||||
misc.adjust_learning_rate(optimizer, data_iter_step / len(data_loader) + epoch, args)
|
||||
|
||||
image1 = image1.to(device, non_blocking=True)
|
||||
image2 = image2.to(device, non_blocking=True)
|
||||
with torch.cuda.amp.autocast(enabled=bool(args.amp)):
|
||||
out, mask, target = model(image1, image2)
|
||||
loss = criterion(out, mask, target)
|
||||
|
||||
loss_value = loss.item()
|
||||
|
||||
if not math.isfinite(loss_value):
|
||||
print("Loss is {}, stopping training".format(loss_value))
|
||||
sys.exit(1)
|
||||
|
||||
loss /= accum_iter
|
||||
loss_scaler(loss, optimizer, parameters=model.parameters(),
|
||||
update_grad=(data_iter_step + 1) % accum_iter == 0)
|
||||
if (data_iter_step + 1) % accum_iter == 0:
|
||||
optimizer.zero_grad()
|
||||
|
||||
torch.cuda.synchronize()
|
||||
|
||||
metric_logger.update(loss=loss_value)
|
||||
|
||||
lr = optimizer.param_groups[0]["lr"]
|
||||
metric_logger.update(lr=lr)
|
||||
|
||||
loss_value_reduce = misc.all_reduce_mean(loss_value)
|
||||
if log_writer is not None and ((data_iter_step + 1) % (accum_iter*args.print_freq)) == 0:
|
||||
# x-axis is based on epoch_1000x in the tensorboard, calibrating differences curves when batch size changes
|
||||
epoch_1000x = int((data_iter_step / len(data_loader) + epoch) * 1000)
|
||||
log_writer.add_scalar('train_loss', loss_value_reduce, epoch_1000x)
|
||||
log_writer.add_scalar('lr', lr, epoch_1000x)
|
||||
|
||||
# gather the stats from all processes
|
||||
metric_logger.synchronize_between_processes()
|
||||
print("Averaged stats:", metric_logger)
|
||||
return {k: meter.global_avg for k, meter in metric_logger.meters.items()}
|
||||
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
args = get_args_parser()
|
||||
args = args.parse_args()
|
||||
main(args)
|
||||
@@ -0,0 +1,318 @@
|
||||
## CroCo-Stereo and CroCo-Flow
|
||||
|
||||
This README explains how to use CroCo-Stereo and CroCo-Flow as well as how they were trained.
|
||||
All commands should be launched from the root directory.
|
||||
|
||||
### Simple inference example
|
||||
|
||||
We provide a simple inference exemple for CroCo-Stereo and CroCo-Flow in the Totebook `croco-stereo-flow-demo.ipynb`.
|
||||
Before running it, please download the trained models with:
|
||||
```
|
||||
bash stereoflow/download_model.sh crocostereo.pth
|
||||
bash stereoflow/download_model.sh crocoflow.pth
|
||||
```
|
||||
|
||||
### Prepare data for training or evaluation
|
||||
|
||||
Put the datasets used for training/evaluation in `./data/stereoflow` (or update the paths at the top of `stereoflow/datasets_stereo.py` and `stereoflow/datasets_flow.py`).
|
||||
Please find below on the file structure should look for each dataset:
|
||||
<details>
|
||||
<summary>FlyingChairs</summary>
|
||||
|
||||
```
|
||||
./data/stereoflow/FlyingChairs/
|
||||
└───chairs_split.txt
|
||||
└───data/
|
||||
└─── ...
|
||||
```
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>MPI-Sintel</summary>
|
||||
|
||||
```
|
||||
./data/stereoflow/MPI-Sintel/
|
||||
└───training/
|
||||
│ └───clean/
|
||||
│ └───final/
|
||||
│ └───flow/
|
||||
└───test/
|
||||
└───clean/
|
||||
└───final/
|
||||
```
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>SceneFlow (including FlyingThings)</summary>
|
||||
|
||||
```
|
||||
./data/stereoflow/SceneFlow/
|
||||
└───Driving/
|
||||
│ └───disparity/
|
||||
│ └───frames_cleanpass/
|
||||
│ └───frames_finalpass/
|
||||
└───FlyingThings/
|
||||
│ └───disparity/
|
||||
│ └───frames_cleanpass/
|
||||
│ └───frames_finalpass/
|
||||
│ └───optical_flow/
|
||||
└───Monkaa/
|
||||
└───disparity/
|
||||
└───frames_cleanpass/
|
||||
└───frames_finalpass/
|
||||
```
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>TartanAir</summary>
|
||||
|
||||
```
|
||||
./data/stereoflow/TartanAir/
|
||||
└───abandonedfactory/
|
||||
│ └───.../
|
||||
└───abandonedfactory_night/
|
||||
│ └───.../
|
||||
└───.../
|
||||
```
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Booster</summary>
|
||||
|
||||
```
|
||||
./data/stereoflow/booster_gt/
|
||||
└───train/
|
||||
└───balanced/
|
||||
└───Bathroom/
|
||||
└───Bedroom/
|
||||
└───...
|
||||
```
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>CREStereo</summary>
|
||||
|
||||
```
|
||||
./data/stereoflow/crenet_stereo_trainset/
|
||||
└───stereo_trainset/
|
||||
└───crestereo/
|
||||
└───hole/
|
||||
└───reflective/
|
||||
└───shapenet/
|
||||
└───tree/
|
||||
```
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>ETH3D Two-view Low-res</summary>
|
||||
|
||||
```
|
||||
./data/stereoflow/eth3d_lowres/
|
||||
└───test/
|
||||
│ └───lakeside_1l/
|
||||
│ └───...
|
||||
└───train/
|
||||
│ └───delivery_area_1l/
|
||||
│ └───...
|
||||
└───train_gt/
|
||||
└───delivery_area_1l/
|
||||
└───...
|
||||
```
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>KITTI 2012</summary>
|
||||
|
||||
```
|
||||
./data/stereoflow/kitti-stereo-2012/
|
||||
└───testing/
|
||||
│ └───colored_0/
|
||||
│ └───colored_1/
|
||||
└───training/
|
||||
└───colored_0/
|
||||
└───colored_1/
|
||||
└───disp_occ/
|
||||
└───flow_occ/
|
||||
```
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>KITTI 2015</summary>
|
||||
|
||||
```
|
||||
./data/stereoflow/kitti-stereo-2015/
|
||||
└───testing/
|
||||
│ └───image_2/
|
||||
│ └───image_3/
|
||||
└───training/
|
||||
└───image_2/
|
||||
└───image_3/
|
||||
└───disp_occ_0/
|
||||
└───flow_occ/
|
||||
```
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Middlebury</summary>
|
||||
|
||||
```
|
||||
./data/stereoflow/middlebury
|
||||
└───2005/
|
||||
│ └───train/
|
||||
│ └───Art/
|
||||
│ └───...
|
||||
└───2006/
|
||||
│ └───Aloe/
|
||||
│ └───Baby1/
|
||||
│ └───...
|
||||
└───2014/
|
||||
│ └───Adirondack-imperfect/
|
||||
│ └───Adirondack-perfect/
|
||||
│ └───...
|
||||
└───2021/
|
||||
│ └───data/
|
||||
│ └───artroom1/
|
||||
│ └───artroom2/
|
||||
│ └───...
|
||||
└───MiddEval3_F/
|
||||
└───test/
|
||||
│ └───Australia/
|
||||
│ └───...
|
||||
└───train/
|
||||
└───Adirondack/
|
||||
└───...
|
||||
```
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Spring</summary>
|
||||
|
||||
```
|
||||
./data/stereoflow/spring/
|
||||
└───test/
|
||||
│ └───0003/
|
||||
│ └───...
|
||||
└───train/
|
||||
└───0001/
|
||||
└───...
|
||||
```
|
||||
</details>
|
||||
|
||||
|
||||
### CroCo-Stereo
|
||||
|
||||
##### Main model
|
||||
|
||||
The main training of CroCo-Stereo was performed on a series of datasets, and it was used as it for Middlebury v3 benchmark.
|
||||
|
||||
```
|
||||
# Download the model
|
||||
bash stereoflow/download_model.sh crocostereo.pth
|
||||
# Middlebury v3 submission
|
||||
python stereoflow/test.py --model stereoflow_models/crocostereo.pth --dataset "MdEval3('all_full')" --save submission --tile_overlap 0.9
|
||||
# Training command that was used, using checkpoint-last.pth
|
||||
python -u stereoflow/train.py stereo --criterion "LaplacianLossBounded2()" --dataset "CREStereo('train')+SceneFlow('train_allpass')+30*ETH3DLowRes('train')+50*Md05('train')+50*Md06('train')+50*Md14('train')+50*Md21('train')+50*MdEval3('train_full')+Booster('train_balanced')" --val_dataset "SceneFlow('test1of100_finalpass')+SceneFlow('test1of100_cleanpass')+ETH3DLowRes('subval')+Md05('subval')+Md06('subval')+Md14('subval')+Md21('subval')+MdEval3('subval_full')+Booster('subval_balanced')" --lr 3e-5 --batch_size 6 --epochs 32 --pretrained pretrained_models/CroCo_V2_ViTLarge_BaseDecoder.pth --output_dir xps/crocostereo/main/
|
||||
# or it can be launched on multiple gpus (while maintaining the effective batch size), e.g. on 3 gpus:
|
||||
torchrun --nproc_per_node 3 stereoflow/train.py stereo --criterion "LaplacianLossBounded2()" --dataset "CREStereo('train')+SceneFlow('train_allpass')+30*ETH3DLowRes('train')+50*Md05('train')+50*Md06('train')+50*Md14('train')+50*Md21('train')+50*MdEval3('train_full')+Booster('train_balanced')" --val_dataset "SceneFlow('test1of100_finalpass')+SceneFlow('test1of100_cleanpass')+ETH3DLowRes('subval')+Md05('subval')+Md06('subval')+Md14('subval')+Md21('subval')+MdEval3('subval_full')+Booster('subval_balanced')" --lr 3e-5 --batch_size 2 --epochs 32 --pretrained pretrained_models/CroCo_V2_ViTLarge_BaseDecoder.pth --output_dir xps/crocostereo/main/
|
||||
```
|
||||
|
||||
For evaluation of validation set, we also provide the model trained on the `subtrain` subset of the training sets.
|
||||
|
||||
```
|
||||
# Download the model
|
||||
bash stereoflow/download_model.sh crocostereo_subtrain.pth
|
||||
# Evaluation on validation sets
|
||||
python stereoflow/test.py --model stereoflow_models/crocostereo_subtrain.pth --dataset "MdEval3('subval_full')+ETH3DLowRes('subval')+SceneFlow('test_finalpass')+SceneFlow('test_cleanpass')" --save metrics --tile_overlap 0.9
|
||||
# Training command that was used (same as above but on subtrain, using checkpoint-best.pth), can also be launched on multiple gpus
|
||||
python -u stereoflow/train.py stereo --criterion "LaplacianLossBounded2()" --dataset "CREStereo('train')+SceneFlow('train_allpass')+30*ETH3DLowRes('subtrain')+50*Md05('subtrain')+50*Md06('subtrain')+50*Md14('subtrain')+50*Md21('subtrain')+50*MdEval3('subtrain_full')+Booster('subtrain_balanced')" --val_dataset "SceneFlow('test1of100_finalpass')+SceneFlow('test1of100_cleanpass')+ETH3DLowRes('subval')+Md05('subval')+Md06('subval')+Md14('subval')+Md21('subval')+MdEval3('subval_full')+Booster('subval_balanced')" --lr 3e-5 --batch_size 6 --epochs 32 --pretrained pretrained_models/CroCo_V2_ViTLarge_BaseDecoder.pth --output_dir xps/crocostereo/main_subtrain/
|
||||
```
|
||||
|
||||
##### Other models
|
||||
|
||||
<details>
|
||||
<summary>Model for ETH3D</summary>
|
||||
The model used for the submission on ETH3D is trained with the same command but using an unbounded Laplacian loss.
|
||||
|
||||
# Download the model
|
||||
bash stereoflow/download_model.sh crocostereo_eth3d.pth
|
||||
# ETH3D submission
|
||||
python stereoflow/test.py --model stereoflow_models/crocostereo_eth3d.pth --dataset "ETH3DLowRes('all')" --save submission --tile_overlap 0.9
|
||||
# Training command that was used
|
||||
python -u stereoflow/train.py stereo --criterion "LaplacianLoss()" --tile_conf_mode conf_expbeta3 --dataset "CREStereo('train')+SceneFlow('train_allpass')+30*ETH3DLowRes('train')+50*Md05('train')+50*Md06('train')+50*Md14('train')+50*Md21('train')+50*MdEval3('train_full')+Booster('train_balanced')" --val_dataset "SceneFlow('test1of100_finalpass')+SceneFlow('test1of100_cleanpass')+ETH3DLowRes('subval')+Md05('subval')+Md06('subval')+Md14('subval')+Md21('subval')+MdEval3('subval_full')+Booster('subval_balanced')" --lr 3e-5 --batch_size 6 --epochs 32 --pretrained pretrained_models/CroCo_V2_ViTLarge_BaseDecoder.pth --output_dir xps/crocostereo/main_eth3d/
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Main model finetuned on Kitti</summary>
|
||||
|
||||
# Download the model
|
||||
bash stereoflow/download_model.sh crocostereo_finetune_kitti.pth
|
||||
# Kitti submission
|
||||
python stereoflow/test.py --model stereoflow_models/crocostereo_finetune_kitti.pth --dataset "Kitti15('test')" --save submission --tile_overlap 0.9
|
||||
# Training that was used
|
||||
python -u stereoflow/train.py stereo --crop 352 1216 --criterion "LaplacianLossBounded2()" --dataset "Kitti12('train')+Kitti15('train')" --lr 3e-5 --batch_size 1 --accum_iter 6 --epochs 20 --pretrained pretrained_models/CroCo_V2_ViTLarge_BaseDecoder.pth --start_from stereoflow_models/crocostereo.pth --output_dir xps/crocostereo/finetune_kitti/ --save_every 5
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Main model finetuned on Spring</summary>
|
||||
|
||||
# Download the model
|
||||
bash stereoflow/download_model.sh crocostereo_finetune_spring.pth
|
||||
# Spring submission
|
||||
python stereoflow/test.py --model stereoflow_models/crocostereo_finetune_spring.pth --dataset "Spring('test')" --save submission --tile_overlap 0.9
|
||||
# Training command that was used
|
||||
python -u stereoflow/train.py stereo --criterion "LaplacianLossBounded2()" --dataset "Spring('train')" --lr 3e-5 --batch_size 6 --epochs 8 --pretrained pretrained_models/CroCo_V2_ViTLarge_BaseDecoder.pth --start_from stereoflow_models/crocostereo.pth --output_dir xps/crocostereo/finetune_spring/
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Smaller models</summary>
|
||||
To train CroCo-Stereo with smaller CroCo pretrained models, simply replace the <code>--pretrained</code> argument. To download the smaller CroCo-Stereo models based on CroCo v2 pretraining with ViT-Base encoder and Small encoder, use <code>bash stereoflow/download_model.sh crocostereo_subtrain_vitb_smalldecoder.pth</code>, and for the model with a ViT-Base encoder and a Base decoder, use <code>bash stereoflow/download_model.sh crocostereo_subtrain_vitb_basedecoder.pth</code>.
|
||||
</details>
|
||||
|
||||
|
||||
### CroCo-Flow
|
||||
|
||||
##### Main model
|
||||
|
||||
The main training of CroCo-Flow was performed on the FlyingThings, FlyingChairs, MPI-Sintel and TartanAir datasets.
|
||||
It was used for our submission to the MPI-Sintel benchmark.
|
||||
|
||||
```
|
||||
# Download the model
|
||||
bash stereoflow/download_model.sh crocoflow.pth
|
||||
# Evaluation
|
||||
python stereoflow/test.py --model stereoflow_models/crocoflow.pth --dataset "MPISintel('subval_cleanpass')+MPISintel('subval_finalpass')" --save metrics --tile_overlap 0.9
|
||||
# Sintel submission
|
||||
python stereoflow/test.py --model stereoflow_models/crocoflow.pth --dataset "MPISintel('test_allpass')" --save submission --tile_overlap 0.9
|
||||
# Training command that was used, with checkpoint-best.pth
|
||||
python -u stereoflow/train.py flow --criterion "LaplacianLossBounded()" --dataset "40*MPISintel('subtrain_cleanpass')+40*MPISintel('subtrain_finalpass')+4*FlyingThings('train_allpass')+4*FlyingChairs('train')+TartanAir('train')" --val_dataset "MPISintel('subval_cleanpass')+MPISintel('subval_finalpass')" --lr 2e-5 --batch_size 8 --epochs 240 --img_per_epoch 30000 --pretrained pretrained_models/CroCo_V2_ViTLarge_BaseDecoder.pth --output_dir xps/crocoflow/main/
|
||||
```
|
||||
|
||||
##### Other models
|
||||
|
||||
<details>
|
||||
<summary>Main model finetuned on Kitti</summary>
|
||||
|
||||
# Download the model
|
||||
bash stereoflow/download_model.sh crocoflow_finetune_kitti.pth
|
||||
# Kitti submission
|
||||
python stereoflow/test.py --model stereoflow_models/crocoflow_finetune_kitti.pth --dataset "Kitti15('test')" --save submission --tile_overlap 0.99
|
||||
# Training that was used, with checkpoint-last.pth
|
||||
python -u stereoflow/train.py flow --crop 352 1216 --criterion "LaplacianLossBounded()" --dataset "Kitti15('train')+Kitti12('train')" --lr 2e-5 --batch_size 1 --accum_iter 8 --epochs 150 --save_every 5 --pretrained pretrained_models/CroCo_V2_ViTLarge_BaseDecoder.pth --start_from stereoflow_models/crocoflow.pth --output_dir xps/crocoflow/finetune_kitti/
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Main model finetuned on Spring</summary>
|
||||
|
||||
# Download the model
|
||||
bash stereoflow/download_model.sh crocoflow_finetune_spring.pth
|
||||
# Spring submission
|
||||
python stereoflow/test.py --model stereoflow_models/crocoflow_finetune_spring.pth --dataset "Spring('test')" --save submission --tile_overlap 0.9
|
||||
# Training command that was used, with checkpoint-last.pth
|
||||
python -u stereoflow/train.py flow --criterion "LaplacianLossBounded()" --dataset "Spring('train')" --lr 2e-5 --batch_size 8 --epochs 12 --pretrained pretrained_models/CroCo_V2_ViTLarge_BaseDecoder.pth --start_from stereoflow_models/crocoflow.pth --output_dir xps/crocoflow/finetune_spring/
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary>Smaller models</summary>
|
||||
To train CroCo-Flow with smaller CroCo pretrained models, simply replace the <code>--pretrained</code> argument. To download the smaller CroCo-Flow models based on CroCo v2 pretraining with ViT-Base encoder and Small encoder, use <code>bash stereoflow/download_model.sh crocoflow_vitb_smalldecoder.pth</code>, and for the model with a ViT-Base encoder and a Base decoder, use <code>bash stereoflow/download_model.sh crocoflow_vitb_basedecoder.pth</code>.
|
||||
</details>
|
||||
@@ -0,0 +1,290 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
# --------------------------------------------------------
|
||||
# Data augmentation for training stereo and flow
|
||||
# --------------------------------------------------------
|
||||
|
||||
# References
|
||||
# https://github.com/autonomousvision/unimatch/blob/master/dataloader/stereo/transforms.py
|
||||
# https://github.com/autonomousvision/unimatch/blob/master/dataloader/flow/transforms.py
|
||||
|
||||
|
||||
import numpy as np
|
||||
import random
|
||||
from PIL import Image
|
||||
|
||||
import cv2
|
||||
cv2.setNumThreads(0)
|
||||
cv2.ocl.setUseOpenCL(False)
|
||||
|
||||
import torch
|
||||
from torchvision.transforms import ColorJitter
|
||||
import torchvision.transforms.functional as FF
|
||||
|
||||
class StereoAugmentor(object):
|
||||
|
||||
def __init__(self, crop_size, scale_prob=0.5, scale_xonly=True, lhth=800., lminscale=0.0, lmaxscale=1.0, hminscale=-0.2, hmaxscale=0.4, scale_interp_nearest=True, rightjitterprob=0.5, v_flip_prob=0.5, color_aug_asym=True, color_choice_prob=0.5):
|
||||
self.crop_size = crop_size
|
||||
self.scale_prob = scale_prob
|
||||
self.scale_xonly = scale_xonly
|
||||
self.lhth = lhth
|
||||
self.lminscale = lminscale
|
||||
self.lmaxscale = lmaxscale
|
||||
self.hminscale = hminscale
|
||||
self.hmaxscale = hmaxscale
|
||||
self.scale_interp_nearest = scale_interp_nearest
|
||||
self.rightjitterprob = rightjitterprob
|
||||
self.v_flip_prob = v_flip_prob
|
||||
self.color_aug_asym = color_aug_asym
|
||||
self.color_choice_prob = color_choice_prob
|
||||
|
||||
def _random_scale(self, img1, img2, disp):
|
||||
ch,cw = self.crop_size
|
||||
h,w = img1.shape[:2]
|
||||
if self.scale_prob>0. and np.random.rand()<self.scale_prob:
|
||||
min_scale, max_scale = (self.lminscale,self.lmaxscale) if min(h,w) < self.lhth else (self.hminscale,self.hmaxscale)
|
||||
scale_x = 2. ** np.random.uniform(min_scale, max_scale)
|
||||
scale_x = np.clip(scale_x, (cw+8) / float(w), None)
|
||||
scale_y = 1.
|
||||
if not self.scale_xonly:
|
||||
scale_y = scale_x
|
||||
scale_y = np.clip(scale_y, (ch+8) / float(h), None)
|
||||
img1 = cv2.resize(img1, None, fx=scale_x, fy=scale_y, interpolation=cv2.INTER_LINEAR)
|
||||
img2 = cv2.resize(img2, None, fx=scale_x, fy=scale_y, interpolation=cv2.INTER_LINEAR)
|
||||
disp = cv2.resize(disp, None, fx=scale_x, fy=scale_y, interpolation=cv2.INTER_LINEAR if not self.scale_interp_nearest else cv2.INTER_NEAREST) * scale_x
|
||||
else: # check if we need to resize to be able to crop
|
||||
h,w = img1.shape[:2]
|
||||
clip_scale = (cw+8) / float(w)
|
||||
if clip_scale>1.:
|
||||
scale_x = clip_scale
|
||||
scale_y = scale_x if not self.scale_xonly else 1.0
|
||||
img1 = cv2.resize(img1, None, fx=scale_x, fy=scale_y, interpolation=cv2.INTER_LINEAR)
|
||||
img2 = cv2.resize(img2, None, fx=scale_x, fy=scale_y, interpolation=cv2.INTER_LINEAR)
|
||||
disp = cv2.resize(disp, None, fx=scale_x, fy=scale_y, interpolation=cv2.INTER_LINEAR if not self.scale_interp_nearest else cv2.INTER_NEAREST) * scale_x
|
||||
return img1, img2, disp
|
||||
|
||||
def _random_crop(self, img1, img2, disp):
|
||||
h,w = img1.shape[:2]
|
||||
ch,cw = self.crop_size
|
||||
assert ch<=h and cw<=w, (img1.shape, h,w,ch,cw)
|
||||
offset_x = np.random.randint(w - cw + 1)
|
||||
offset_y = np.random.randint(h - ch + 1)
|
||||
img1 = img1[offset_y:offset_y+ch,offset_x:offset_x+cw]
|
||||
img2 = img2[offset_y:offset_y+ch,offset_x:offset_x+cw]
|
||||
disp = disp[offset_y:offset_y+ch,offset_x:offset_x+cw]
|
||||
return img1, img2, disp
|
||||
|
||||
def _random_vflip(self, img1, img2, disp):
|
||||
# vertical flip
|
||||
if self.v_flip_prob>0 and np.random.rand() < self.v_flip_prob:
|
||||
img1 = np.copy(np.flipud(img1))
|
||||
img2 = np.copy(np.flipud(img2))
|
||||
disp = np.copy(np.flipud(disp))
|
||||
return img1, img2, disp
|
||||
|
||||
def _random_rotate_shift_right(self, img2):
|
||||
if self.rightjitterprob>0. and np.random.rand()<self.rightjitterprob:
|
||||
angle, pixel = 0.1, 2
|
||||
px = np.random.uniform(-pixel, pixel)
|
||||
ag = np.random.uniform(-angle, angle)
|
||||
image_center = (np.random.uniform(0, img2.shape[0]), np.random.uniform(0, img2.shape[1]) )
|
||||
rot_mat = cv2.getRotationMatrix2D(image_center, ag, 1.0)
|
||||
img2 = cv2.warpAffine(img2, rot_mat, img2.shape[1::-1], flags=cv2.INTER_LINEAR)
|
||||
trans_mat = np.float32([[1, 0, 0], [0, 1, px]])
|
||||
img2 = cv2.warpAffine(img2, trans_mat, img2.shape[1::-1], flags=cv2.INTER_LINEAR)
|
||||
return img2
|
||||
|
||||
def _random_color_contrast(self, img1, img2):
|
||||
if np.random.random() < 0.5:
|
||||
contrast_factor = np.random.uniform(0.8, 1.2)
|
||||
img1 = FF.adjust_contrast(img1, contrast_factor)
|
||||
if self.color_aug_asym and np.random.random() < 0.5: contrast_factor = np.random.uniform(0.8, 1.2)
|
||||
img2 = FF.adjust_contrast(img2, contrast_factor)
|
||||
return img1, img2
|
||||
def _random_color_gamma(self, img1, img2):
|
||||
if np.random.random() < 0.5:
|
||||
gamma = np.random.uniform(0.7, 1.5)
|
||||
img1 = FF.adjust_gamma(img1, gamma)
|
||||
if self.color_aug_asym and np.random.random() < 0.5: gamma = np.random.uniform(0.7, 1.5)
|
||||
img2 = FF.adjust_gamma(img2, gamma)
|
||||
return img1, img2
|
||||
def _random_color_brightness(self, img1, img2):
|
||||
if np.random.random() < 0.5:
|
||||
brightness = np.random.uniform(0.5, 2.0)
|
||||
img1 = FF.adjust_brightness(img1, brightness)
|
||||
if self.color_aug_asym and np.random.random() < 0.5: brightness = np.random.uniform(0.5, 2.0)
|
||||
img2 = FF.adjust_brightness(img2, brightness)
|
||||
return img1, img2
|
||||
def _random_color_hue(self, img1, img2):
|
||||
if np.random.random() < 0.5:
|
||||
hue = np.random.uniform(-0.1, 0.1)
|
||||
img1 = FF.adjust_hue(img1, hue)
|
||||
if self.color_aug_asym and np.random.random() < 0.5: hue = np.random.uniform(-0.1, 0.1)
|
||||
img2 = FF.adjust_hue(img2, hue)
|
||||
return img1, img2
|
||||
def _random_color_saturation(self, img1, img2):
|
||||
if np.random.random() < 0.5:
|
||||
saturation = np.random.uniform(0.8, 1.2)
|
||||
img1 = FF.adjust_saturation(img1, saturation)
|
||||
if self.color_aug_asym and np.random.random() < 0.5: saturation = np.random.uniform(-0.8,1.2)
|
||||
img2 = FF.adjust_saturation(img2, saturation)
|
||||
return img1, img2
|
||||
def _random_color(self, img1, img2):
|
||||
trfs = [self._random_color_contrast,self._random_color_gamma,self._random_color_brightness,self._random_color_hue,self._random_color_saturation]
|
||||
img1 = Image.fromarray(img1.astype('uint8'))
|
||||
img2 = Image.fromarray(img2.astype('uint8'))
|
||||
if np.random.random() < self.color_choice_prob:
|
||||
# A single transform
|
||||
t = random.choice(trfs)
|
||||
img1, img2 = t(img1, img2)
|
||||
else:
|
||||
# Combination of trfs
|
||||
# Random order
|
||||
random.shuffle(trfs)
|
||||
for t in trfs:
|
||||
img1, img2 = t(img1, img2)
|
||||
img1 = np.array(img1).astype(np.float32)
|
||||
img2 = np.array(img2).astype(np.float32)
|
||||
return img1, img2
|
||||
|
||||
def __call__(self, img1, img2, disp, dataset_name):
|
||||
img1, img2, disp = self._random_scale(img1, img2, disp)
|
||||
img1, img2, disp = self._random_crop(img1, img2, disp)
|
||||
img1, img2, disp = self._random_vflip(img1, img2, disp)
|
||||
img2 = self._random_rotate_shift_right(img2)
|
||||
img1, img2 = self._random_color(img1, img2)
|
||||
return img1, img2, disp
|
||||
|
||||
|
||||
|
||||
class FlowAugmentor:
|
||||
|
||||
def __init__(self, crop_size, min_scale=-0.2, max_scale=0.5, spatial_aug_prob=0.8, stretch_prob=0.8, max_stretch=0.2, h_flip_prob=0.5, v_flip_prob=0.1, asymmetric_color_aug_prob=0.2):
|
||||
|
||||
# spatial augmentation params
|
||||
self.crop_size = crop_size
|
||||
self.min_scale = min_scale
|
||||
self.max_scale = max_scale
|
||||
self.spatial_aug_prob = spatial_aug_prob
|
||||
self.stretch_prob = stretch_prob
|
||||
self.max_stretch = max_stretch
|
||||
|
||||
# flip augmentation params
|
||||
self.h_flip_prob = h_flip_prob
|
||||
self.v_flip_prob = v_flip_prob
|
||||
|
||||
# photometric augmentation params
|
||||
self.photo_aug = ColorJitter(brightness=0.4, contrast=0.4, saturation=0.4, hue=0.5 / 3.14)
|
||||
|
||||
self.asymmetric_color_aug_prob = asymmetric_color_aug_prob
|
||||
|
||||
def color_transform(self, img1, img2):
|
||||
""" Photometric augmentation """
|
||||
|
||||
# asymmetric
|
||||
if np.random.rand() < self.asymmetric_color_aug_prob:
|
||||
img1 = np.array(self.photo_aug(Image.fromarray(img1)), dtype=np.uint8)
|
||||
img2 = np.array(self.photo_aug(Image.fromarray(img2)), dtype=np.uint8)
|
||||
|
||||
# symmetric
|
||||
else:
|
||||
image_stack = np.concatenate([img1, img2], axis=0)
|
||||
image_stack = np.array(self.photo_aug(Image.fromarray(image_stack)), dtype=np.uint8)
|
||||
img1, img2 = np.split(image_stack, 2, axis=0)
|
||||
|
||||
return img1, img2
|
||||
|
||||
def _resize_flow(self, flow, scale_x, scale_y, factor=1.0):
|
||||
if np.all(np.isfinite(flow)):
|
||||
flow = cv2.resize(flow, None, fx=scale_x/factor, fy=scale_y/factor, interpolation=cv2.INTER_LINEAR)
|
||||
flow = flow * [scale_x, scale_y]
|
||||
else: # sparse version
|
||||
fx, fy = scale_x, scale_y
|
||||
ht, wd = flow.shape[:2]
|
||||
coords = np.meshgrid(np.arange(wd), np.arange(ht))
|
||||
coords = np.stack(coords, axis=-1)
|
||||
|
||||
coords = coords.reshape(-1, 2).astype(np.float32)
|
||||
flow = flow.reshape(-1, 2).astype(np.float32)
|
||||
valid = np.isfinite(flow[:,0])
|
||||
|
||||
coords0 = coords[valid]
|
||||
flow0 = flow[valid]
|
||||
|
||||
ht1 = int(round(ht * fy/factor))
|
||||
wd1 = int(round(wd * fx/factor))
|
||||
|
||||
rescale = np.expand_dims(np.array([fx, fy]), axis=0)
|
||||
coords1 = coords0 * rescale / factor
|
||||
flow1 = flow0 * rescale
|
||||
|
||||
xx = np.round(coords1[:, 0]).astype(np.int32)
|
||||
yy = np.round(coords1[:, 1]).astype(np.int32)
|
||||
|
||||
v = (xx > 0) & (xx < wd1) & (yy > 0) & (yy < ht1)
|
||||
xx = xx[v]
|
||||
yy = yy[v]
|
||||
flow1 = flow1[v]
|
||||
|
||||
flow = np.inf * np.ones([ht1, wd1, 2], dtype=np.float32) # invalid value every where, before we fill it with the correct ones
|
||||
flow[yy, xx] = flow1
|
||||
return flow
|
||||
|
||||
def spatial_transform(self, img1, img2, flow, dname):
|
||||
|
||||
if np.random.rand() < self.spatial_aug_prob:
|
||||
# randomly sample scale
|
||||
ht, wd = img1.shape[:2]
|
||||
clip_min_scale = np.maximum(
|
||||
(self.crop_size[0] + 8) / float(ht),
|
||||
(self.crop_size[1] + 8) / float(wd))
|
||||
min_scale, max_scale = self.min_scale, self.max_scale
|
||||
scale = 2 ** np.random.uniform(self.min_scale, self.max_scale)
|
||||
scale_x = scale
|
||||
scale_y = scale
|
||||
if np.random.rand() < self.stretch_prob:
|
||||
scale_x *= 2 ** np.random.uniform(-self.max_stretch, self.max_stretch)
|
||||
scale_y *= 2 ** np.random.uniform(-self.max_stretch, self.max_stretch)
|
||||
scale_x = np.clip(scale_x, clip_min_scale, None)
|
||||
scale_y = np.clip(scale_y, clip_min_scale, None)
|
||||
# rescale the images
|
||||
img1 = cv2.resize(img1, None, fx=scale_x, fy=scale_y, interpolation=cv2.INTER_LINEAR)
|
||||
img2 = cv2.resize(img2, None, fx=scale_x, fy=scale_y, interpolation=cv2.INTER_LINEAR)
|
||||
flow = self._resize_flow(flow, scale_x, scale_y, factor=2.0 if dname=='Spring' else 1.0)
|
||||
elif dname=="Spring":
|
||||
flow = self._resize_flow(flow, 1.0, 1.0, factor=2.0)
|
||||
|
||||
if self.h_flip_prob>0. and np.random.rand() < self.h_flip_prob: # h-flip
|
||||
img1 = img1[:, ::-1]
|
||||
img2 = img2[:, ::-1]
|
||||
flow = flow[:, ::-1] * [-1.0, 1.0]
|
||||
|
||||
if self.v_flip_prob>0. and np.random.rand() < self.v_flip_prob: # v-flip
|
||||
img1 = img1[::-1, :]
|
||||
img2 = img2[::-1, :]
|
||||
flow = flow[::-1, :] * [1.0, -1.0]
|
||||
|
||||
# In case no cropping
|
||||
if img1.shape[0] - self.crop_size[0] > 0:
|
||||
y0 = np.random.randint(0, img1.shape[0] - self.crop_size[0])
|
||||
else:
|
||||
y0 = 0
|
||||
if img1.shape[1] - self.crop_size[1] > 0:
|
||||
x0 = np.random.randint(0, img1.shape[1] - self.crop_size[1])
|
||||
else:
|
||||
x0 = 0
|
||||
|
||||
img1 = img1[y0:y0 + self.crop_size[0], x0:x0 + self.crop_size[1]]
|
||||
img2 = img2[y0:y0 + self.crop_size[0], x0:x0 + self.crop_size[1]]
|
||||
flow = flow[y0:y0 + self.crop_size[0], x0:x0 + self.crop_size[1]]
|
||||
|
||||
return img1, img2, flow
|
||||
|
||||
def __call__(self, img1, img2, flow, dname):
|
||||
img1, img2, flow = self.spatial_transform(img1, img2, flow, dname)
|
||||
img1, img2 = self.color_transform(img1, img2)
|
||||
img1 = np.ascontiguousarray(img1)
|
||||
img2 = np.ascontiguousarray(img2)
|
||||
flow = np.ascontiguousarray(flow)
|
||||
return img1, img2, flow
|
||||
@@ -0,0 +1,251 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
# --------------------------------------------------------
|
||||
# Losses, metrics per batch, metrics per dataset
|
||||
# --------------------------------------------------------
|
||||
|
||||
import torch
|
||||
from torch import nn
|
||||
import torch.nn.functional as F
|
||||
|
||||
def _get_gtnorm(gt):
|
||||
if gt.size(1)==1: # stereo
|
||||
return gt
|
||||
# flow
|
||||
return torch.sqrt(torch.sum(gt**2, dim=1, keepdims=True)) # Bx1xHxW
|
||||
|
||||
############ losses without confidence
|
||||
|
||||
class L1Loss(nn.Module):
|
||||
|
||||
def __init__(self, max_gtnorm=None):
|
||||
super().__init__()
|
||||
self.max_gtnorm = max_gtnorm
|
||||
self.with_conf = False
|
||||
|
||||
def _error(self, gt, predictions):
|
||||
return torch.abs(gt-predictions)
|
||||
|
||||
def forward(self, predictions, gt, inspect=False):
|
||||
mask = torch.isfinite(gt)
|
||||
if self.max_gtnorm is not None:
|
||||
mask *= _get_gtnorm(gt).expand(-1,gt.size(1),-1,-1)<self.max_gtnorm
|
||||
if inspect:
|
||||
return self._error(gt, predictions)
|
||||
return self._error(gt[mask],predictions[mask]).mean()
|
||||
|
||||
############## losses with confience
|
||||
## there are several parametrizations
|
||||
|
||||
class LaplacianLoss(nn.Module): # used for CroCo-Stereo on ETH3D, d'=exp(d)
|
||||
|
||||
def __init__(self, max_gtnorm=None):
|
||||
super().__init__()
|
||||
self.max_gtnorm = max_gtnorm
|
||||
self.with_conf = True
|
||||
|
||||
def forward(self, predictions, gt, conf):
|
||||
mask = torch.isfinite(gt)
|
||||
mask = mask[:,0,:,:]
|
||||
if self.max_gtnorm is not None: mask *= _get_gtnorm(gt)[:,0,:,:]<self.max_gtnorm
|
||||
conf = conf.squeeze(1)
|
||||
return ( torch.abs(gt-predictions).sum(dim=1)[mask] / torch.exp(conf[mask]) + conf[mask] ).mean()# + torch.log(2) => which is a constant
|
||||
|
||||
|
||||
class LaplacianLossBounded(nn.Module): # used for CroCo-Flow ; in the equation of the paper, we have a=1/b
|
||||
def __init__(self, max_gtnorm=10000., a=0.25, b=4.):
|
||||
super().__init__()
|
||||
self.max_gtnorm = max_gtnorm
|
||||
self.with_conf = True
|
||||
self.a, self.b = a, b
|
||||
|
||||
def forward(self, predictions, gt, conf):
|
||||
mask = torch.isfinite(gt)
|
||||
mask = mask[:,0,:,:]
|
||||
if self.max_gtnorm is not None: mask *= _get_gtnorm(gt)[:,0,:,:]<self.max_gtnorm
|
||||
conf = conf.squeeze(1)
|
||||
conf = (self.b - self.a) * torch.sigmoid(conf) + self.a
|
||||
return ( torch.abs(gt-predictions).sum(dim=1)[mask] / conf[mask] + torch.log(conf)[mask] ).mean()# + torch.log(2) => which is a constant
|
||||
|
||||
class LaplacianLossBounded2(nn.Module): # used for CroCo-Stereo (except for ETH3D) ; in the equation of the paper, we have a=b
|
||||
def __init__(self, max_gtnorm=None, a=3.0, b=3.0):
|
||||
super().__init__()
|
||||
self.max_gtnorm = max_gtnorm
|
||||
self.with_conf = True
|
||||
self.a, self.b = a, b
|
||||
|
||||
def forward(self, predictions, gt, conf):
|
||||
mask = torch.isfinite(gt)
|
||||
mask = mask[:,0,:,:]
|
||||
if self.max_gtnorm is not None: mask *= _get_gtnorm(gt)[:,0,:,:]<self.max_gtnorm
|
||||
conf = conf.squeeze(1)
|
||||
conf = 2 * self.a * (torch.sigmoid(conf / self.b) - 0.5 )
|
||||
return ( torch.abs(gt-predictions).sum(dim=1)[mask] / torch.exp(conf[mask]) + conf[mask] ).mean()# + torch.log(2) => which is a constant
|
||||
|
||||
############## metrics per batch
|
||||
|
||||
class StereoMetrics(nn.Module):
|
||||
|
||||
def __init__(self, do_quantile=False):
|
||||
super().__init__()
|
||||
self.bad_ths = [0.5,1,2,3]
|
||||
self.do_quantile = do_quantile
|
||||
|
||||
def forward(self, predictions, gt):
|
||||
B = predictions.size(0)
|
||||
metrics = {}
|
||||
gtcopy = gt.clone()
|
||||
mask = torch.isfinite(gtcopy)
|
||||
gtcopy[~mask] = 999999.0 # we make a copy and put a non-infinite value, such that it does not become nan once multiplied by the mask value 0
|
||||
Npx = mask.view(B,-1).sum(dim=1)
|
||||
L1error = (torch.abs(gtcopy-predictions)*mask).view(B,-1)
|
||||
L2error = (torch.square(gtcopy-predictions)*mask).view(B,-1)
|
||||
# avgerr
|
||||
metrics['avgerr'] = torch.mean(L1error.sum(dim=1)/Npx )
|
||||
# rmse
|
||||
metrics['rmse'] = torch.sqrt(L2error.sum(dim=1)/Npx).mean(dim=0)
|
||||
# err > t for t in [0.5,1,2,3]
|
||||
for ths in self.bad_ths:
|
||||
metrics['bad@{:.1f}'.format(ths)] = (((L1error>ths)* mask.view(B,-1)).sum(dim=1)/Npx).mean(dim=0) * 100
|
||||
return metrics
|
||||
|
||||
class FlowMetrics(nn.Module):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.bad_ths = [1,3,5]
|
||||
|
||||
def forward(self, predictions, gt):
|
||||
B = predictions.size(0)
|
||||
metrics = {}
|
||||
mask = torch.isfinite(gt[:,0,:,:]) # both x and y would be infinite
|
||||
Npx = mask.view(B,-1).sum(dim=1)
|
||||
gtcopy = gt.clone() # to compute L1/L2 error, we need to have non-infinite value, the error computed at this locations will be ignored
|
||||
gtcopy[:,0,:,:][~mask] = 999999.0
|
||||
gtcopy[:,1,:,:][~mask] = 999999.0
|
||||
L1error = (torch.abs(gtcopy-predictions).sum(dim=1)*mask).view(B,-1)
|
||||
L2error = (torch.sqrt(torch.sum(torch.square(gtcopy-predictions),dim=1))*mask).view(B,-1)
|
||||
metrics['L1err'] = torch.mean(L1error.sum(dim=1)/Npx )
|
||||
metrics['EPE'] = torch.mean(L2error.sum(dim=1)/Npx )
|
||||
for ths in self.bad_ths:
|
||||
metrics['bad@{:.1f}'.format(ths)] = (((L2error>ths)* mask.view(B,-1)).sum(dim=1)/Npx).mean(dim=0) * 100
|
||||
return metrics
|
||||
|
||||
############## metrics per dataset
|
||||
## we update the average and maintain the number of pixels while adding data batch per batch
|
||||
## at the beggining, call reset()
|
||||
## after each batch, call add_batch(...)
|
||||
## at the end: call get_results()
|
||||
|
||||
class StereoDatasetMetrics(nn.Module):
|
||||
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.bad_ths = [0.5,1,2,3]
|
||||
|
||||
def reset(self):
|
||||
self.agg_N = 0 # number of pixels so far
|
||||
self.agg_L1err = torch.tensor(0.0) # L1 error so far
|
||||
self.agg_Nbad = [0 for _ in self.bad_ths] # counter of bad pixels
|
||||
self._metrics = None
|
||||
|
||||
def add_batch(self, predictions, gt):
|
||||
assert predictions.size(1)==1, predictions.size()
|
||||
assert gt.size(1)==1, gt.size()
|
||||
if gt.size(2)==predictions.size(2)*2 and gt.size(3)==predictions.size(3)*2: # special case for Spring ...
|
||||
L1err = torch.minimum( torch.minimum( torch.minimum(
|
||||
torch.sum(torch.abs(gt[:,:,0::2,0::2]-predictions),dim=1),
|
||||
torch.sum(torch.abs(gt[:,:,1::2,0::2]-predictions),dim=1)),
|
||||
torch.sum(torch.abs(gt[:,:,0::2,1::2]-predictions),dim=1)),
|
||||
torch.sum(torch.abs(gt[:,:,1::2,1::2]-predictions),dim=1))
|
||||
valid = torch.isfinite(L1err)
|
||||
else:
|
||||
valid = torch.isfinite(gt[:,0,:,:]) # both x and y would be infinite
|
||||
L1err = torch.sum(torch.abs(gt-predictions),dim=1)
|
||||
N = valid.sum()
|
||||
Nnew = self.agg_N + N
|
||||
self.agg_L1err = float(self.agg_N)/Nnew * self.agg_L1err + L1err[valid].mean().cpu() * float(N)/Nnew
|
||||
self.agg_N = Nnew
|
||||
for i,th in enumerate(self.bad_ths):
|
||||
self.agg_Nbad[i] += (L1err[valid]>th).sum().cpu()
|
||||
|
||||
def _compute_metrics(self):
|
||||
if self._metrics is not None: return
|
||||
out = {}
|
||||
out['L1err'] = self.agg_L1err.item()
|
||||
for i,th in enumerate(self.bad_ths):
|
||||
out['bad@{:.1f}'.format(th)] = (float(self.agg_Nbad[i]) / self.agg_N).item() * 100.0
|
||||
self._metrics = out
|
||||
|
||||
def get_results(self):
|
||||
self._compute_metrics() # to avoid recompute them multiple times
|
||||
return self._metrics
|
||||
|
||||
class FlowDatasetMetrics(nn.Module):
|
||||
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.bad_ths = [0.5,1,3,5]
|
||||
self.speed_ths = [(0,10),(10,40),(40,torch.inf)]
|
||||
|
||||
def reset(self):
|
||||
self.agg_N = 0 # number of pixels so far
|
||||
self.agg_L1err = torch.tensor(0.0) # L1 error so far
|
||||
self.agg_L2err = torch.tensor(0.0) # L2 (=EPE) error so far
|
||||
self.agg_Nbad = [0 for _ in self.bad_ths] # counter of bad pixels
|
||||
self.agg_EPEspeed = [torch.tensor(0.0) for _ in self.speed_ths] # EPE per speed bin so far
|
||||
self.agg_Nspeed = [0 for _ in self.speed_ths] # N pixels per speed bin so far
|
||||
self._metrics = None
|
||||
self.pairname_results = {}
|
||||
|
||||
def add_batch(self, predictions, gt):
|
||||
assert predictions.size(1)==2, predictions.size()
|
||||
assert gt.size(1)==2, gt.size()
|
||||
if gt.size(2)==predictions.size(2)*2 and gt.size(3)==predictions.size(3)*2: # special case for Spring ...
|
||||
L1err = torch.minimum( torch.minimum( torch.minimum(
|
||||
torch.sum(torch.abs(gt[:,:,0::2,0::2]-predictions),dim=1),
|
||||
torch.sum(torch.abs(gt[:,:,1::2,0::2]-predictions),dim=1)),
|
||||
torch.sum(torch.abs(gt[:,:,0::2,1::2]-predictions),dim=1)),
|
||||
torch.sum(torch.abs(gt[:,:,1::2,1::2]-predictions),dim=1))
|
||||
L2err = torch.minimum( torch.minimum( torch.minimum(
|
||||
torch.sqrt(torch.sum(torch.square(gt[:,:,0::2,0::2]-predictions),dim=1)),
|
||||
torch.sqrt(torch.sum(torch.square(gt[:,:,1::2,0::2]-predictions),dim=1))),
|
||||
torch.sqrt(torch.sum(torch.square(gt[:,:,0::2,1::2]-predictions),dim=1))),
|
||||
torch.sqrt(torch.sum(torch.square(gt[:,:,1::2,1::2]-predictions),dim=1)))
|
||||
valid = torch.isfinite(L1err)
|
||||
gtspeed = (torch.sqrt(torch.sum(torch.square(gt[:,:,0::2,0::2]),dim=1)) + torch.sqrt(torch.sum(torch.square(gt[:,:,0::2,1::2]),dim=1)) +\
|
||||
torch.sqrt(torch.sum(torch.square(gt[:,:,1::2,0::2]),dim=1)) + torch.sqrt(torch.sum(torch.square(gt[:,:,1::2,1::2]),dim=1)) ) / 4.0 # let's just average them
|
||||
else:
|
||||
valid = torch.isfinite(gt[:,0,:,:]) # both x and y would be infinite
|
||||
L1err = torch.sum(torch.abs(gt-predictions),dim=1)
|
||||
L2err = torch.sqrt(torch.sum(torch.square(gt-predictions),dim=1))
|
||||
gtspeed = torch.sqrt(torch.sum(torch.square(gt),dim=1))
|
||||
N = valid.sum()
|
||||
Nnew = self.agg_N + N
|
||||
self.agg_L1err = float(self.agg_N)/Nnew * self.agg_L1err + L1err[valid].mean().cpu() * float(N)/Nnew
|
||||
self.agg_L2err = float(self.agg_N)/Nnew * self.agg_L2err + L2err[valid].mean().cpu() * float(N)/Nnew
|
||||
self.agg_N = Nnew
|
||||
for i,th in enumerate(self.bad_ths):
|
||||
self.agg_Nbad[i] += (L2err[valid]>th).sum().cpu()
|
||||
for i,(th1,th2) in enumerate(self.speed_ths):
|
||||
vv = (gtspeed[valid]>=th1) * (gtspeed[valid]<th2)
|
||||
iNspeed = vv.sum()
|
||||
if iNspeed==0: continue
|
||||
iNnew = self.agg_Nspeed[i] + iNspeed
|
||||
self.agg_EPEspeed[i] = float(self.agg_Nspeed[i]) / iNnew * self.agg_EPEspeed[i] + float(iNspeed) / iNnew * L2err[valid][vv].mean().cpu()
|
||||
self.agg_Nspeed[i] = iNnew
|
||||
|
||||
def _compute_metrics(self):
|
||||
if self._metrics is not None: return
|
||||
out = {}
|
||||
out['L1err'] = self.agg_L1err.item()
|
||||
out['EPE'] = self.agg_L2err.item()
|
||||
for i,th in enumerate(self.bad_ths):
|
||||
out['bad@{:.1f}'.format(th)] = (float(self.agg_Nbad[i]) / self.agg_N).item() * 100.0
|
||||
for i,(th1,th2) in enumerate(self.speed_ths):
|
||||
out['s{:d}{:s}'.format(th1, '-'+str(th2) if th2<torch.inf else '+')] = self.agg_EPEspeed[i].item()
|
||||
self._metrics = out
|
||||
|
||||
def get_results(self):
|
||||
self._compute_metrics() # to avoid recompute them multiple times
|
||||
return self._metrics
|
||||
@@ -0,0 +1,630 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
# --------------------------------------------------------
|
||||
# Dataset structure for flow
|
||||
# --------------------------------------------------------
|
||||
|
||||
import os
|
||||
import os.path as osp
|
||||
import pickle
|
||||
import numpy as np
|
||||
import struct
|
||||
from PIL import Image
|
||||
import json
|
||||
import h5py
|
||||
import torch
|
||||
from torch.utils import data
|
||||
|
||||
from .augmentor import FlowAugmentor
|
||||
from .datasets_stereo import _read_img, img_to_tensor, dataset_to_root, _read_pfm
|
||||
from copy import deepcopy
|
||||
dataset_to_root = deepcopy(dataset_to_root)
|
||||
|
||||
dataset_to_root.update(**{
|
||||
'TartanAir': './data/stereoflow/TartanAir',
|
||||
'FlyingChairs': './data/stereoflow/FlyingChairs/',
|
||||
'FlyingThings': osp.join(dataset_to_root['SceneFlow'],'FlyingThings')+'/',
|
||||
'MPISintel': './data/stereoflow//MPI-Sintel/'+'/',
|
||||
})
|
||||
cache_dir = "./data/stereoflow/datasets_flow_cache/"
|
||||
|
||||
|
||||
def flow_to_tensor(disp):
|
||||
return torch.from_numpy(disp).float().permute(2, 0, 1)
|
||||
|
||||
class FlowDataset(data.Dataset):
|
||||
|
||||
def __init__(self, split, augmentor=False, crop_size=None, totensor=True):
|
||||
self.split = split
|
||||
if not augmentor: assert crop_size is None
|
||||
if crop_size is not None: assert augmentor
|
||||
self.crop_size = crop_size
|
||||
self.augmentor_str = augmentor
|
||||
self.augmentor = FlowAugmentor(crop_size) if augmentor else None
|
||||
self.totensor = totensor
|
||||
self.rmul = 1 # keep track of rmul
|
||||
self.has_constant_resolution = True # whether the dataset has constant resolution or not (=> don't use batch_size>1 at test time)
|
||||
self._prepare_data()
|
||||
self._load_or_build_cache()
|
||||
|
||||
def prepare_data(self):
|
||||
"""
|
||||
to be defined for each dataset
|
||||
"""
|
||||
raise NotImplementedError
|
||||
|
||||
def __len__(self):
|
||||
return len(self.pairnames) # each pairname is typically of the form (str, int1, int2)
|
||||
|
||||
def __getitem__(self, index):
|
||||
pairname = self.pairnames[index]
|
||||
|
||||
# get filenames
|
||||
img1name = self.pairname_to_img1name(pairname)
|
||||
img2name = self.pairname_to_img2name(pairname)
|
||||
flowname = self.pairname_to_flowname(pairname) if self.pairname_to_flowname is not None else None
|
||||
|
||||
# load images and disparities
|
||||
img1 = _read_img(img1name)
|
||||
img2 = _read_img(img2name)
|
||||
flow = self.load_flow(flowname) if flowname is not None else None
|
||||
|
||||
# apply augmentations
|
||||
if self.augmentor is not None:
|
||||
img1, img2, flow = self.augmentor(img1, img2, flow, self.name)
|
||||
|
||||
if self.totensor:
|
||||
img1 = img_to_tensor(img1)
|
||||
img2 = img_to_tensor(img2)
|
||||
if flow is not None:
|
||||
flow = flow_to_tensor(flow)
|
||||
else:
|
||||
flow = torch.tensor([]) # to allow dataloader batching with default collate_gn
|
||||
pairname = str(pairname) # transform potential tuple to str to be able to batch it
|
||||
|
||||
return img1, img2, flow, pairname
|
||||
|
||||
def __rmul__(self, v):
|
||||
self.rmul *= v
|
||||
self.pairnames = v * self.pairnames
|
||||
return self
|
||||
|
||||
def __str__(self):
|
||||
return f'{self.__class__.__name__}_{self.split}'
|
||||
|
||||
def __repr__(self):
|
||||
s = f'{self.__class__.__name__}(split={self.split}, augmentor={self.augmentor_str}, crop_size={str(self.crop_size)}, totensor={self.totensor})'
|
||||
if self.rmul==1:
|
||||
s+=f'\n\tnum pairs: {len(self.pairnames)}'
|
||||
else:
|
||||
s+=f'\n\tnum pairs: {len(self.pairnames)} ({len(self.pairnames)//self.rmul}x{self.rmul})'
|
||||
return s
|
||||
|
||||
def _set_root(self):
|
||||
self.root = dataset_to_root[self.name]
|
||||
assert os.path.isdir(self.root), f"could not find root directory for dataset {self.name}: {self.root}"
|
||||
|
||||
def _load_or_build_cache(self):
|
||||
cache_file = osp.join(cache_dir, self.name+'.pkl')
|
||||
if osp.isfile(cache_file):
|
||||
with open(cache_file, 'rb') as fid:
|
||||
self.pairnames = pickle.load(fid)[self.split]
|
||||
else:
|
||||
tosave = self._build_cache()
|
||||
os.makedirs(cache_dir, exist_ok=True)
|
||||
with open(cache_file, 'wb') as fid:
|
||||
pickle.dump(tosave, fid)
|
||||
self.pairnames = tosave[self.split]
|
||||
|
||||
class TartanAirDataset(FlowDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "TartanAir"
|
||||
self._set_root()
|
||||
assert self.split in ['train']
|
||||
self.pairname_to_img1name = lambda pairname: osp.join(self.root, pairname[0], 'image_left/{:06d}_left.png'.format(pairname[1]))
|
||||
self.pairname_to_img2name = lambda pairname: osp.join(self.root, pairname[0], 'image_left/{:06d}_left.png'.format(pairname[2]))
|
||||
self.pairname_to_flowname = lambda pairname: osp.join(self.root, pairname[0], 'flow/{:06d}_{:06d}_flow.npy'.format(pairname[1],pairname[2]))
|
||||
self.pairname_to_str = lambda pairname: os.path.join(pairname[0][pairname[0].find('/')+1:], '{:06d}_{:06d}'.format(pairname[1], pairname[2]))
|
||||
self.load_flow = _read_numpy_flow
|
||||
|
||||
def _build_cache(self):
|
||||
seqs = sorted(os.listdir(self.root))
|
||||
pairs = [(osp.join(s,s,difficulty,Pxxx),int(a[:6]),int(a[:6])+1) for s in seqs for difficulty in ['Easy','Hard'] for Pxxx in sorted(os.listdir(osp.join(self.root,s,s,difficulty))) for a in sorted(os.listdir(osp.join(self.root,s,s,difficulty,Pxxx,'image_left/')))[:-1]]
|
||||
assert len(pairs)==306268, "incorrect parsing of pairs in TartanAir"
|
||||
tosave = {'train': pairs}
|
||||
return tosave
|
||||
|
||||
class FlyingChairsDataset(FlowDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "FlyingChairs"
|
||||
self._set_root()
|
||||
assert self.split in ['train','val']
|
||||
self.pairname_to_img1name = lambda pairname: osp.join(self.root, 'data', pairname+'_img1.ppm')
|
||||
self.pairname_to_img2name = lambda pairname: osp.join(self.root, 'data', pairname+'_img2.ppm')
|
||||
self.pairname_to_flowname = lambda pairname: osp.join(self.root, 'data', pairname+'_flow.flo')
|
||||
self.pairname_to_str = lambda pairname: pairname
|
||||
self.load_flow = _read_flo_file
|
||||
|
||||
def _build_cache(self):
|
||||
split_file = osp.join(self.root, 'chairs_split.txt')
|
||||
split_list = np.loadtxt(split_file, dtype=np.int32)
|
||||
trainpairs = ['{:05d}'.format(i) for i in np.where(split_list==1)[0]+1]
|
||||
valpairs = ['{:05d}'.format(i) for i in np.where(split_list==2)[0]+1]
|
||||
assert len(trainpairs)==22232 and len(valpairs)==640, "incorrect parsing of pairs in MPI-Sintel"
|
||||
tosave = {'train': trainpairs, 'val': valpairs}
|
||||
return tosave
|
||||
|
||||
class FlyingThingsDataset(FlowDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "FlyingThings"
|
||||
self._set_root()
|
||||
assert self.split in [f'{set_}_{pass_}pass{camstr}' for set_ in ['train','test','test1024'] for camstr in ['','_rightcam'] for pass_ in ['clean','final','all']]
|
||||
self.pairname_to_img1name = lambda pairname: osp.join(self.root, f'frames_{pairname[3]}pass', pairname[0].replace('into_future','').replace('into_past',''), '{:04d}.png'.format(pairname[1]))
|
||||
self.pairname_to_img2name = lambda pairname: osp.join(self.root, f'frames_{pairname[3]}pass', pairname[0].replace('into_future','').replace('into_past',''), '{:04d}.png'.format(pairname[2]))
|
||||
self.pairname_to_flowname = lambda pairname: osp.join(self.root, 'optical_flow', pairname[0], 'OpticalFlowInto{f:s}_{i:04d}_{c:s}.pfm'.format(f='Future' if 'future' in pairname[0] else 'Past', i=pairname[1], c='L' if 'left' in pairname[0] else 'R' ))
|
||||
self.pairname_to_str = lambda pairname: os.path.join(pairname[3]+'pass', pairname[0], 'Into{f:s}_{i:04d}_{c:s}'.format(f='Future' if 'future' in pairname[0] else 'Past', i=pairname[1], c='L' if 'left' in pairname[0] else 'R' ))
|
||||
self.load_flow = _read_pfm_flow
|
||||
|
||||
def _build_cache(self):
|
||||
tosave = {}
|
||||
# train and test splits for the different passes
|
||||
for set_ in ['train', 'test']:
|
||||
sroot = osp.join(self.root, 'optical_flow', set_.upper())
|
||||
fname_to_i = lambda f: int(f[len('OpticalFlowIntoFuture_'):-len('_L.pfm')])
|
||||
pp = [(osp.join(set_.upper(), d, s, 'into_future/left'),fname_to_i(fname)) for d in sorted(os.listdir(sroot)) for s in sorted(os.listdir(osp.join(sroot,d))) for fname in sorted(os.listdir(osp.join(sroot,d, s, 'into_future/left')))[:-1]]
|
||||
pairs = [(a,i,i+1) for a,i in pp]
|
||||
pairs += [(a.replace('into_future','into_past'),i+1,i) for a,i in pp]
|
||||
assert len(pairs)=={'train': 40302, 'test': 7866}[set_], "incorrect parsing of pairs Flying Things"
|
||||
for cam in ['left','right']:
|
||||
camstr = '' if cam=='left' else f'_{cam}cam'
|
||||
for pass_ in ['final', 'clean']:
|
||||
tosave[f'{set_}_{pass_}pass{camstr}'] = [(a.replace('left',cam),i,j,pass_) for a,i,j in pairs]
|
||||
tosave[f'{set_}_allpass{camstr}'] = tosave[f'{set_}_cleanpass{camstr}'] + tosave[f'{set_}_finalpass{camstr}']
|
||||
# test1024: this is the same split as unimatch 'validation' split
|
||||
# see https://github.com/autonomousvision/unimatch/blob/master/dataloader/flow/datasets.py#L229
|
||||
test1024_nsamples = 1024
|
||||
alltest_nsamples = len(tosave['test_cleanpass']) # 7866
|
||||
stride = alltest_nsamples // test1024_nsamples
|
||||
remove = alltest_nsamples % test1024_nsamples
|
||||
for cam in ['left','right']:
|
||||
camstr = '' if cam=='left' else f'_{cam}cam'
|
||||
for pass_ in ['final','clean']:
|
||||
tosave[f'test1024_{pass_}pass{camstr}'] = sorted(tosave[f'test_{pass_}pass{camstr}'])[:-remove][::stride] # warning, it was not sorted before
|
||||
assert len(tosave['test1024_cleanpass'])==1024, "incorrect parsing of pairs in Flying Things"
|
||||
tosave[f'test1024_allpass{camstr}'] = tosave[f'test1024_cleanpass{camstr}'] + tosave[f'test1024_finalpass{camstr}']
|
||||
return tosave
|
||||
|
||||
|
||||
class MPISintelDataset(FlowDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "MPISintel"
|
||||
self._set_root()
|
||||
assert self.split in [s+'_'+p for s in ['train','test','subval','subtrain'] for p in ['cleanpass','finalpass','allpass']]
|
||||
self.pairname_to_img1name = lambda pairname: osp.join(self.root, pairname[0], 'frame_{:04d}.png'.format(pairname[1]))
|
||||
self.pairname_to_img2name = lambda pairname: osp.join(self.root, pairname[0], 'frame_{:04d}.png'.format(pairname[1]+1))
|
||||
self.pairname_to_flowname = lambda pairname: None if pairname[0].startswith('test/') else osp.join(self.root, pairname[0].replace('/clean/','/flow/').replace('/final/','/flow/'), 'frame_{:04d}.flo'.format(pairname[1]))
|
||||
self.pairname_to_str = lambda pairname: osp.join(pairname[0], 'frame_{:04d}'.format(pairname[1]))
|
||||
self.load_flow = _read_flo_file
|
||||
|
||||
def _build_cache(self):
|
||||
trainseqs = sorted(os.listdir(self.root+'training/clean'))
|
||||
trainpairs = [ (osp.join('training/clean', s),i) for s in trainseqs for i in range(1, len(os.listdir(self.root+'training/clean/'+s)))]
|
||||
subvalseqs = ['temple_2','temple_3']
|
||||
subtrainseqs = [s for s in trainseqs if s not in subvalseqs]
|
||||
subvalpairs = [ (p,i) for p,i in trainpairs if any(s in p for s in subvalseqs)]
|
||||
subtrainpairs = [ (p,i) for p,i in trainpairs if any(s in p for s in subtrainseqs)]
|
||||
testseqs = sorted(os.listdir(self.root+'test/clean'))
|
||||
testpairs = [ (osp.join('test/clean', s),i) for s in testseqs for i in range(1, len(os.listdir(self.root+'test/clean/'+s)))]
|
||||
assert len(trainpairs)==1041 and len(testpairs)==552 and len(subvalpairs)==98 and len(subtrainpairs)==943, "incorrect parsing of pairs in MPI-Sintel"
|
||||
tosave = {}
|
||||
tosave['train_cleanpass'] = trainpairs
|
||||
tosave['test_cleanpass'] = testpairs
|
||||
tosave['subval_cleanpass'] = subvalpairs
|
||||
tosave['subtrain_cleanpass'] = subtrainpairs
|
||||
for t in ['train','test','subval','subtrain']:
|
||||
tosave[t+'_finalpass'] = [(p.replace('/clean/','/final/'),i) for p,i in tosave[t+'_cleanpass']]
|
||||
tosave[t+'_allpass'] = tosave[t+'_cleanpass'] + tosave[t+'_finalpass']
|
||||
return tosave
|
||||
|
||||
def submission_save_pairname(self, pairname, prediction, outdir, _time):
|
||||
assert prediction.shape[2]==2
|
||||
outfile = os.path.join(outdir, 'submission', self.pairname_to_str(pairname)+'.flo')
|
||||
os.makedirs( os.path.dirname(outfile), exist_ok=True)
|
||||
writeFlowFile(prediction, outfile)
|
||||
|
||||
def finalize_submission(self, outdir):
|
||||
assert self.split == 'test_allpass'
|
||||
bundle_exe = "/nfs/data/ffs-3d/datasets/StereoFlow/MPI-Sintel/bundler/linux-x64/bundler" # eg <bundle_exe> <path_to_results_for_clean> <path_to_results_for_final> <output/bundled.lzma>
|
||||
if os.path.isfile(bundle_exe):
|
||||
cmd = f'{bundle_exe} "{outdir}/submission/test/clean/" "{outdir}/submission/test/final" "{outdir}/submission/bundled.lzma"'
|
||||
print(cmd)
|
||||
os.system(cmd)
|
||||
print(f'Done. Submission file at: "{outdir}/submission/bundled.lzma"')
|
||||
else:
|
||||
print('Could not find bundler executable for submission.')
|
||||
print('Please download it and run:')
|
||||
print(f'<bundle_exe> "{outdir}/submission/test/clean/" "{outdir}/submission/test/final" "{outdir}/submission/bundled.lzma"')
|
||||
|
||||
class SpringDataset(FlowDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "Spring"
|
||||
self._set_root()
|
||||
assert self.split in ['train','test','subtrain','subval']
|
||||
self.pairname_to_img1name = lambda pairname: osp.join(self.root, pairname[0], pairname[1], 'frame_'+pairname[3], 'frame_{:s}_{:04d}.png'.format(pairname[3], pairname[4]))
|
||||
self.pairname_to_img2name = lambda pairname: osp.join(self.root, pairname[0], pairname[1], 'frame_'+pairname[3], 'frame_{:s}_{:04d}.png'.format(pairname[3], pairname[4]+(1 if pairname[2]=='FW' else -1)))
|
||||
self.pairname_to_flowname = lambda pairname: None if pairname[0]=='test' else osp.join(self.root, pairname[0], pairname[1], f'flow_{pairname[2]}_{pairname[3]}', f'flow_{pairname[2]}_{pairname[3]}_{pairname[4]:04d}.flo5')
|
||||
self.pairname_to_str = lambda pairname: osp.join(pairname[0], pairname[1], f'flow_{pairname[2]}_{pairname[3]}', f'flow_{pairname[2]}_{pairname[3]}_{pairname[4]:04d}')
|
||||
self.load_flow = _read_hdf5_flow
|
||||
|
||||
def _build_cache(self):
|
||||
# train
|
||||
trainseqs = sorted(os.listdir( osp.join(self.root,'train')))
|
||||
trainpairs = []
|
||||
for leftright in ['left','right']:
|
||||
for fwbw in ['FW','BW']:
|
||||
trainpairs += [('train',s,fwbw,leftright,int(f[len(f'flow_{fwbw}_{leftright}_'):-len('.flo5')])) for s in trainseqs for f in sorted(os.listdir(osp.join(self.root,'train',s,f'flow_{fwbw}_{leftright}')))]
|
||||
# test
|
||||
testseqs = sorted(os.listdir( osp.join(self.root,'test')))
|
||||
testpairs = []
|
||||
for leftright in ['left','right']:
|
||||
testpairs += [('test',s,'FW',leftright,int(f[len(f'frame_{leftright}_'):-len('.png')])) for s in testseqs for f in sorted(os.listdir(osp.join(self.root,'test',s,f'frame_{leftright}')))[:-1]]
|
||||
testpairs += [('test',s,'BW',leftright,int(f[len(f'frame_{leftright}_'):-len('.png')])+1) for s in testseqs for f in sorted(os.listdir(osp.join(self.root,'test',s,f'frame_{leftright}')))[:-1]]
|
||||
# subtrain / subval
|
||||
subtrainpairs = [p for p in trainpairs if p[1]!='0041']
|
||||
subvalpairs = [p for p in trainpairs if p[1]=='0041']
|
||||
assert len(trainpairs)==19852 and len(testpairs)==3960 and len(subtrainpairs)==19472 and len(subvalpairs)==380, "incorrect parsing of pairs in Spring"
|
||||
tosave = {'train': trainpairs, 'test': testpairs, 'subtrain': subtrainpairs, 'subval': subvalpairs}
|
||||
return tosave
|
||||
|
||||
def submission_save_pairname(self, pairname, prediction, outdir, time):
|
||||
assert prediction.ndim==3
|
||||
assert prediction.shape[2]==2
|
||||
assert prediction.dtype==np.float32
|
||||
outfile = osp.join(outdir, pairname[0], pairname[1], f'flow_{pairname[2]}_{pairname[3]}', f'flow_{pairname[2]}_{pairname[3]}_{pairname[4]:04d}.flo5')
|
||||
os.makedirs( os.path.dirname(outfile), exist_ok=True)
|
||||
writeFlo5File(prediction, outfile)
|
||||
|
||||
def finalize_submission(self, outdir):
|
||||
assert self.split=='test'
|
||||
exe = "{self.root}/flow_subsampling"
|
||||
if os.path.isfile(exe):
|
||||
cmd = f'cd "{outdir}/test"; {exe} .'
|
||||
print(cmd)
|
||||
os.system(cmd)
|
||||
print(f'Done. Submission file at {outdir}/test/flow_submission.hdf5')
|
||||
else:
|
||||
print('Could not find flow_subsampling executable for submission.')
|
||||
print('Please download it and run:')
|
||||
print(f'cd "{outdir}/test"; <flow_subsampling_exe> .')
|
||||
|
||||
|
||||
class Kitti12Dataset(FlowDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "Kitti12"
|
||||
self._set_root()
|
||||
assert self.split in ['train','test']
|
||||
self.pairname_to_img1name = lambda pairname: osp.join(self.root, pairname+'_10.png')
|
||||
self.pairname_to_img2name = lambda pairname: osp.join(self.root, pairname+'_11.png')
|
||||
self.pairname_to_flowname = None if self.split=='test' else lambda pairname: osp.join(self.root, pairname.replace('/colored_0/','/flow_occ/')+'_10.png')
|
||||
self.pairname_to_str = lambda pairname: pairname.replace('/colored_0/','/')
|
||||
self.load_flow = _read_kitti_flow
|
||||
|
||||
def _build_cache(self):
|
||||
trainseqs = ["training/colored_0/%06d"%(i) for i in range(194)]
|
||||
testseqs = ["testing/colored_0/%06d"%(i) for i in range(195)]
|
||||
assert len(trainseqs)==194 and len(testseqs)==195, "incorrect parsing of pairs in Kitti12"
|
||||
tosave = {'train': trainseqs, 'test': testseqs}
|
||||
return tosave
|
||||
|
||||
def submission_save_pairname(self, pairname, prediction, outdir, time):
|
||||
assert prediction.ndim==3
|
||||
assert prediction.shape[2]==2
|
||||
outfile = os.path.join(outdir, pairname.split('/')[-1]+'_10.png')
|
||||
os.makedirs( os.path.dirname(outfile), exist_ok=True)
|
||||
writeFlowKitti(outfile, prediction)
|
||||
|
||||
def finalize_submission(self, outdir):
|
||||
assert self.split=='test'
|
||||
cmd = f'cd {outdir}/; zip -r "kitti12_flow_results.zip" .'
|
||||
print(cmd)
|
||||
os.system(cmd)
|
||||
print(f'Done. Submission file at {outdir}/kitti12_flow_results.zip')
|
||||
|
||||
|
||||
class Kitti15Dataset(FlowDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "Kitti15"
|
||||
self._set_root()
|
||||
assert self.split in ['train','subtrain','subval','test']
|
||||
self.pairname_to_img1name = lambda pairname: osp.join(self.root, pairname+'_10.png')
|
||||
self.pairname_to_img2name = lambda pairname: osp.join(self.root, pairname+'_11.png')
|
||||
self.pairname_to_flowname = None if self.split=='test' else lambda pairname: osp.join(self.root, pairname.replace('/image_2/','/flow_occ/')+'_10.png')
|
||||
self.pairname_to_str = lambda pairname: pairname.replace('/image_2/','/')
|
||||
self.load_flow = _read_kitti_flow
|
||||
|
||||
def _build_cache(self):
|
||||
trainseqs = ["training/image_2/%06d"%(i) for i in range(200)]
|
||||
subtrainseqs = trainseqs[:-10]
|
||||
subvalseqs = trainseqs[-10:]
|
||||
testseqs = ["testing/image_2/%06d"%(i) for i in range(200)]
|
||||
assert len(trainseqs)==200 and len(subtrainseqs)==190 and len(subvalseqs)==10 and len(testseqs)==200, "incorrect parsing of pairs in Kitti15"
|
||||
tosave = {'train': trainseqs, 'subtrain': subtrainseqs, 'subval': subvalseqs, 'test': testseqs}
|
||||
return tosave
|
||||
|
||||
def submission_save_pairname(self, pairname, prediction, outdir, time):
|
||||
assert prediction.ndim==3
|
||||
assert prediction.shape[2]==2
|
||||
outfile = os.path.join(outdir, 'flow', pairname.split('/')[-1]+'_10.png')
|
||||
os.makedirs( os.path.dirname(outfile), exist_ok=True)
|
||||
writeFlowKitti(outfile, prediction)
|
||||
|
||||
def finalize_submission(self, outdir):
|
||||
assert self.split=='test'
|
||||
cmd = f'cd {outdir}/; zip -r "kitti15_flow_results.zip" flow'
|
||||
print(cmd)
|
||||
os.system(cmd)
|
||||
print(f'Done. Submission file at {outdir}/kitti15_flow_results.zip')
|
||||
|
||||
|
||||
import cv2
|
||||
def _read_numpy_flow(filename):
|
||||
return np.load(filename)
|
||||
|
||||
def _read_pfm_flow(filename):
|
||||
f, _ = _read_pfm(filename)
|
||||
assert np.all(f[:,:,2]==0.0)
|
||||
return np.ascontiguousarray(f[:,:,:2])
|
||||
|
||||
TAG_FLOAT = 202021.25 # tag to check the sanity of the file
|
||||
TAG_STRING = 'PIEH' # string containing the tag
|
||||
MIN_WIDTH = 1
|
||||
MAX_WIDTH = 99999
|
||||
MIN_HEIGHT = 1
|
||||
MAX_HEIGHT = 99999
|
||||
def readFlowFile(filename):
|
||||
"""
|
||||
readFlowFile(<FILENAME>) reads a flow file <FILENAME> into a 2-band np.array.
|
||||
if <FILENAME> does not exist, an IOError is raised.
|
||||
if <FILENAME> does not finish by '.flo' or the tag, the width, the height or the file's size is illegal, an Expcetion is raised.
|
||||
---- PARAMETERS ----
|
||||
filename: string containg the name of the file to read a flow
|
||||
---- OUTPUTS ----
|
||||
a np.array of dimension (height x width x 2) containing the flow of type 'float32'
|
||||
"""
|
||||
|
||||
# check filename
|
||||
if not filename.endswith(".flo"):
|
||||
raise Exception("readFlowFile({:s}): filename must finish with '.flo'".format(filename))
|
||||
|
||||
# open the file and read it
|
||||
with open(filename,'rb') as f:
|
||||
# check tag
|
||||
tag = struct.unpack('f',f.read(4))[0]
|
||||
if tag != TAG_FLOAT:
|
||||
raise Exception("flow_utils.readFlowFile({:s}): wrong tag".format(filename))
|
||||
# read dimension
|
||||
w,h = struct.unpack('ii',f.read(8))
|
||||
if w < MIN_WIDTH or w > MAX_WIDTH:
|
||||
raise Exception("flow_utils.readFlowFile({:s}: illegal width {:d}".format(filename,w))
|
||||
if h < MIN_HEIGHT or h > MAX_HEIGHT:
|
||||
raise Exception("flow_utils.readFlowFile({:s}: illegal height {:d}".format(filename,h))
|
||||
flow = np.fromfile(f,'float32')
|
||||
if not flow.shape == (h*w*2,):
|
||||
raise Exception("flow_utils.readFlowFile({:s}: illegal size of the file".format(filename))
|
||||
flow.shape = (h,w,2)
|
||||
return flow
|
||||
|
||||
def writeFlowFile(flow,filename):
|
||||
"""
|
||||
writeFlowFile(flow,<FILENAME>) write flow to the file <FILENAME>.
|
||||
if <FILENAME> does not exist, an IOError is raised.
|
||||
if <FILENAME> does not finish with '.flo' or the flow has not 2 bands, an Exception is raised.
|
||||
---- PARAMETERS ----
|
||||
flow: np.array of dimension (height x width x 2) containing the flow to write
|
||||
filename: string containg the name of the file to write a flow
|
||||
"""
|
||||
|
||||
# check filename
|
||||
if not filename.endswith(".flo"):
|
||||
raise Exception("flow_utils.writeFlowFile(<flow>,{:s}): filename must finish with '.flo'".format(filename))
|
||||
|
||||
if not flow.shape[2:] == (2,):
|
||||
raise Exception("flow_utils.writeFlowFile(<flow>,{:s}): <flow> must have 2 bands".format(filename))
|
||||
|
||||
|
||||
# open the file and write it
|
||||
with open(filename,'wb') as f:
|
||||
# write TAG
|
||||
f.write( TAG_STRING.encode('utf-8') )
|
||||
# write dimension
|
||||
f.write( struct.pack('ii',flow.shape[1],flow.shape[0]) )
|
||||
# write the flow
|
||||
|
||||
flow.astype(np.float32).tofile(f)
|
||||
|
||||
_read_flo_file = readFlowFile
|
||||
|
||||
def _read_kitti_flow(filename):
|
||||
flow = cv2.imread(filename, cv2.IMREAD_ANYDEPTH | cv2.IMREAD_COLOR)
|
||||
flow = flow[:, :, ::-1].astype(np.float32)
|
||||
valid = flow[:, :, 2]>0
|
||||
flow = flow[:, :, :2]
|
||||
flow = (flow - 2 ** 15) / 64.0
|
||||
flow[~valid,0] = np.inf
|
||||
flow[~valid,1] = np.inf
|
||||
return flow
|
||||
_read_hd1k_flow = _read_kitti_flow
|
||||
|
||||
|
||||
def writeFlowKitti(filename, uv):
|
||||
uv = 64.0 * uv + 2 ** 15
|
||||
valid = np.ones([uv.shape[0], uv.shape[1], 1])
|
||||
uv = np.concatenate([uv, valid], axis=-1).astype(np.uint16)
|
||||
cv2.imwrite(filename, uv[..., ::-1])
|
||||
|
||||
def writeFlo5File(flow, filename):
|
||||
with h5py.File(filename, "w") as f:
|
||||
f.create_dataset("flow", data=flow, compression="gzip", compression_opts=5)
|
||||
|
||||
def _read_hdf5_flow(filename):
|
||||
flow = np.asarray(h5py.File(filename)['flow'])
|
||||
flow[np.isnan(flow)] = np.inf # make invalid values as +inf
|
||||
return flow.astype(np.float32)
|
||||
|
||||
# flow visualization
|
||||
RY = 15
|
||||
YG = 6
|
||||
GC = 4
|
||||
CB = 11
|
||||
BM = 13
|
||||
MR = 6
|
||||
UNKNOWN_THRESH = 1e9
|
||||
|
||||
def colorTest():
|
||||
"""
|
||||
flow_utils.colorTest(): display an example of image showing the color encoding scheme
|
||||
"""
|
||||
import matplotlib.pylab as plt
|
||||
truerange = 1
|
||||
h,w = 151,151
|
||||
trange = truerange*1.04
|
||||
s2 = round(h/2)
|
||||
x,y = np.meshgrid(range(w),range(h))
|
||||
u = x*trange/s2-trange
|
||||
v = y*trange/s2-trange
|
||||
img = _computeColor(np.concatenate((u[:,:,np.newaxis],v[:,:,np.newaxis]),2)/trange/np.sqrt(2))
|
||||
plt.imshow(img)
|
||||
plt.axis('off')
|
||||
plt.axhline(round(h/2),color='k')
|
||||
plt.axvline(round(w/2),color='k')
|
||||
|
||||
def flowToColor(flow, maxflow=None, maxmaxflow=None, saturate=False):
|
||||
"""
|
||||
flow_utils.flowToColor(flow): return a color code flow field, normalized based on the maximum l2-norm of the flow
|
||||
flow_utils.flowToColor(flow,maxflow): return a color code flow field, normalized by maxflow
|
||||
---- PARAMETERS ----
|
||||
flow: flow to display of shape (height x width x 2)
|
||||
maxflow (default:None): if given, normalize the flow by its value, otherwise by the flow norm
|
||||
maxmaxflow (default:None): if given, normalize the flow by the max of its value and the flow norm
|
||||
---- OUTPUT ----
|
||||
an np.array of shape (height x width x 3) of type uint8 containing a color code of the flow
|
||||
"""
|
||||
h,w,n = flow.shape
|
||||
# check size of flow
|
||||
assert n == 2, "flow_utils.flowToColor(flow): flow must have 2 bands"
|
||||
# fix unknown flow
|
||||
unknown_idx = np.max(np.abs(flow),2)>UNKNOWN_THRESH
|
||||
flow[unknown_idx] = 0.0
|
||||
# compute max flow if needed
|
||||
if maxflow is None:
|
||||
maxflow = flowMaxNorm(flow)
|
||||
if maxmaxflow is not None:
|
||||
maxflow = min(maxmaxflow, maxflow)
|
||||
# normalize flow
|
||||
eps = np.spacing(1) # minimum positive float value to avoid division by 0
|
||||
# compute the flow
|
||||
img = _computeColor(flow/(maxflow+eps), saturate=saturate)
|
||||
# put black pixels in unknown location
|
||||
img[ np.tile( unknown_idx[:,:,np.newaxis],[1,1,3]) ] = 0.0
|
||||
return img
|
||||
|
||||
def flowMaxNorm(flow):
|
||||
"""
|
||||
flow_utils.flowMaxNorm(flow): return the maximum of the l2-norm of the given flow
|
||||
---- PARAMETERS ----
|
||||
flow: the flow
|
||||
|
||||
---- OUTPUT ----
|
||||
a float containing the maximum of the l2-norm of the flow
|
||||
"""
|
||||
return np.max( np.sqrt( np.sum( np.square( flow ) , 2) ) )
|
||||
|
||||
def _computeColor(flow, saturate=True):
|
||||
"""
|
||||
flow_utils._computeColor(flow): compute color codes for the flow field flow
|
||||
|
||||
---- PARAMETERS ----
|
||||
flow: np.array of dimension (height x width x 2) containing the flow to display
|
||||
---- OUTPUTS ----
|
||||
an np.array of dimension (height x width x 3) containing the color conversion of the flow
|
||||
"""
|
||||
# set nan to 0
|
||||
nanidx = np.isnan(flow[:,:,0])
|
||||
flow[nanidx] = 0.0
|
||||
|
||||
# colorwheel
|
||||
ncols = RY + YG + GC + CB + BM + MR
|
||||
nchans = 3
|
||||
colorwheel = np.zeros((ncols,nchans),'uint8')
|
||||
col = 0;
|
||||
#RY
|
||||
colorwheel[:RY,0] = 255
|
||||
colorwheel[:RY,1] = [(255*i) // RY for i in range(RY)]
|
||||
col += RY
|
||||
# YG
|
||||
colorwheel[col:col+YG,0] = [255 - (255*i) // YG for i in range(YG)]
|
||||
colorwheel[col:col+YG,1] = 255
|
||||
col += YG
|
||||
# GC
|
||||
colorwheel[col:col+GC,1] = 255
|
||||
colorwheel[col:col+GC,2] = [(255*i) // GC for i in range(GC)]
|
||||
col += GC
|
||||
# CB
|
||||
colorwheel[col:col+CB,1] = [255 - (255*i) // CB for i in range(CB)]
|
||||
colorwheel[col:col+CB,2] = 255
|
||||
col += CB
|
||||
# BM
|
||||
colorwheel[col:col+BM,0] = [(255*i) // BM for i in range(BM)]
|
||||
colorwheel[col:col+BM,2] = 255
|
||||
col += BM
|
||||
# MR
|
||||
colorwheel[col:col+MR,0] = 255
|
||||
colorwheel[col:col+MR,2] = [255 - (255*i) // MR for i in range(MR)]
|
||||
|
||||
# compute utility variables
|
||||
rad = np.sqrt( np.sum( np.square(flow) , 2) ) # magnitude
|
||||
a = np.arctan2( -flow[:,:,1] , -flow[:,:,0]) / np.pi # angle
|
||||
fk = (a+1)/2 * (ncols-1) # map [-1,1] to [0,ncols-1]
|
||||
k0 = np.floor(fk).astype('int')
|
||||
k1 = k0+1
|
||||
k1[k1==ncols] = 0
|
||||
f = fk-k0
|
||||
|
||||
if not saturate:
|
||||
rad = np.minimum(rad,1)
|
||||
|
||||
# compute the image
|
||||
img = np.zeros( (flow.shape[0],flow.shape[1],nchans), 'uint8' )
|
||||
for i in range(nchans):
|
||||
tmp = colorwheel[:,i].astype('float')
|
||||
col0 = tmp[k0]/255
|
||||
col1 = tmp[k1]/255
|
||||
col = (1-f)*col0 + f*col1
|
||||
idx = (rad <= 1)
|
||||
col[idx] = 1-rad[idx]*(1-col[idx]) # increase saturation with radius
|
||||
col[~idx] *= 0.75 # out of range
|
||||
img[:,:,i] = (255*col*(1-nanidx.astype('float'))).astype('uint8')
|
||||
|
||||
return img
|
||||
|
||||
# flow dataset getter
|
||||
|
||||
def get_train_dataset_flow(dataset_str, augmentor=True, crop_size=None):
|
||||
dataset_str = dataset_str.replace('(','Dataset(')
|
||||
if augmentor:
|
||||
dataset_str = dataset_str.replace(')',', augmentor=True)')
|
||||
if crop_size is not None:
|
||||
dataset_str = dataset_str.replace(')',', crop_size={:s})'.format(str(crop_size)))
|
||||
return eval(dataset_str)
|
||||
|
||||
def get_test_datasets_flow(dataset_str):
|
||||
dataset_str = dataset_str.replace('(','Dataset(')
|
||||
return [eval(s) for s in dataset_str.split('+')]
|
||||
@@ -0,0 +1,674 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
# --------------------------------------------------------
|
||||
# Dataset structure for stereo
|
||||
# --------------------------------------------------------
|
||||
|
||||
import sys, os
|
||||
import os.path as osp
|
||||
import pickle
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
import json
|
||||
import h5py
|
||||
from glob import glob
|
||||
import cv2
|
||||
|
||||
import torch
|
||||
from torch.utils import data
|
||||
|
||||
from .augmentor import StereoAugmentor
|
||||
|
||||
|
||||
|
||||
dataset_to_root = {
|
||||
'CREStereo': './data/stereoflow//crenet_stereo_trainset/stereo_trainset/crestereo/',
|
||||
'SceneFlow': './data/stereoflow//SceneFlow/',
|
||||
'ETH3DLowRes': './data/stereoflow/eth3d_lowres/',
|
||||
'Booster': './data/stereoflow/booster_gt/',
|
||||
'Middlebury2021': './data/stereoflow/middlebury/2021/data/',
|
||||
'Middlebury2014': './data/stereoflow/middlebury/2014/',
|
||||
'Middlebury2006': './data/stereoflow/middlebury/2006/',
|
||||
'Middlebury2005': './data/stereoflow/middlebury/2005/train/',
|
||||
'MiddleburyEval3': './data/stereoflow/middlebury/MiddEval3/',
|
||||
'Spring': './data/stereoflow/spring/',
|
||||
'Kitti15': './data/stereoflow/kitti-stereo-2015/',
|
||||
'Kitti12': './data/stereoflow/kitti-stereo-2012/',
|
||||
}
|
||||
cache_dir = "./data/stereoflow/datasets_stereo_cache/"
|
||||
|
||||
|
||||
in1k_mean = torch.tensor([0.485, 0.456, 0.406]).view(3,1,1)
|
||||
in1k_std = torch.tensor([0.229, 0.224, 0.225]).view(3,1,1)
|
||||
def img_to_tensor(img):
|
||||
img = torch.from_numpy(img).permute(2, 0, 1).float() / 255.
|
||||
img = (img-in1k_mean)/in1k_std
|
||||
return img
|
||||
def disp_to_tensor(disp):
|
||||
return torch.from_numpy(disp)[None,:,:]
|
||||
|
||||
class StereoDataset(data.Dataset):
|
||||
|
||||
def __init__(self, split, augmentor=False, crop_size=None, totensor=True):
|
||||
self.split = split
|
||||
if not augmentor: assert crop_size is None
|
||||
if crop_size: assert augmentor
|
||||
self.crop_size = crop_size
|
||||
self.augmentor_str = augmentor
|
||||
self.augmentor = StereoAugmentor(crop_size) if augmentor else None
|
||||
self.totensor = totensor
|
||||
self.rmul = 1 # keep track of rmul
|
||||
self.has_constant_resolution = True # whether the dataset has constant resolution or not (=> don't use batch_size>1 at test time)
|
||||
self._prepare_data()
|
||||
self._load_or_build_cache()
|
||||
|
||||
def prepare_data(self):
|
||||
"""
|
||||
to be defined for each dataset
|
||||
"""
|
||||
raise NotImplementedError
|
||||
|
||||
def __len__(self):
|
||||
return len(self.pairnames)
|
||||
|
||||
def __getitem__(self, index):
|
||||
pairname = self.pairnames[index]
|
||||
|
||||
# get filenames
|
||||
Limgname = self.pairname_to_Limgname(pairname)
|
||||
Rimgname = self.pairname_to_Rimgname(pairname)
|
||||
Ldispname = self.pairname_to_Ldispname(pairname) if self.pairname_to_Ldispname is not None else None
|
||||
|
||||
# load images and disparities
|
||||
Limg = _read_img(Limgname)
|
||||
Rimg = _read_img(Rimgname)
|
||||
disp = self.load_disparity(Ldispname) if Ldispname is not None else None
|
||||
|
||||
# sanity check
|
||||
if disp is not None: assert np.all(disp>0) or self.name=="Spring", (self.name, pairname, Ldispname)
|
||||
|
||||
# apply augmentations
|
||||
if self.augmentor is not None:
|
||||
Limg, Rimg, disp = self.augmentor(Limg, Rimg, disp, self.name)
|
||||
|
||||
if self.totensor:
|
||||
Limg = img_to_tensor(Limg)
|
||||
Rimg = img_to_tensor(Rimg)
|
||||
if disp is None:
|
||||
disp = torch.tensor([]) # to allow dataloader batching with default collate_gn
|
||||
else:
|
||||
disp = disp_to_tensor(disp)
|
||||
|
||||
return Limg, Rimg, disp, str(pairname)
|
||||
|
||||
def __rmul__(self, v):
|
||||
self.rmul *= v
|
||||
self.pairnames = v * self.pairnames
|
||||
return self
|
||||
|
||||
def __str__(self):
|
||||
return f'{self.__class__.__name__}_{self.split}'
|
||||
|
||||
def __repr__(self):
|
||||
s = f'{self.__class__.__name__}(split={self.split}, augmentor={self.augmentor_str}, crop_size={str(self.crop_size)}, totensor={self.totensor})'
|
||||
if self.rmul==1:
|
||||
s+=f'\n\tnum pairs: {len(self.pairnames)}'
|
||||
else:
|
||||
s+=f'\n\tnum pairs: {len(self.pairnames)} ({len(self.pairnames)//self.rmul}x{self.rmul})'
|
||||
return s
|
||||
|
||||
def _set_root(self):
|
||||
self.root = dataset_to_root[self.name]
|
||||
assert os.path.isdir(self.root), f"could not find root directory for dataset {self.name}: {self.root}"
|
||||
|
||||
def _load_or_build_cache(self):
|
||||
cache_file = osp.join(cache_dir, self.name+'.pkl')
|
||||
if osp.isfile(cache_file):
|
||||
with open(cache_file, 'rb') as fid:
|
||||
self.pairnames = pickle.load(fid)[self.split]
|
||||
else:
|
||||
tosave = self._build_cache()
|
||||
os.makedirs(cache_dir, exist_ok=True)
|
||||
with open(cache_file, 'wb') as fid:
|
||||
pickle.dump(tosave, fid)
|
||||
self.pairnames = tosave[self.split]
|
||||
|
||||
class CREStereoDataset(StereoDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = 'CREStereo'
|
||||
self._set_root()
|
||||
assert self.split in ['train']
|
||||
self.pairname_to_Limgname = lambda pairname: osp.join(self.root, pairname+'_left.jpg')
|
||||
self.pairname_to_Rimgname = lambda pairname: osp.join(self.root, pairname+'_right.jpg')
|
||||
self.pairname_to_Ldispname = lambda pairname: osp.join(self.root, pairname+'_left.disp.png')
|
||||
self.pairname_to_str = lambda pairname: pairname
|
||||
self.load_disparity = _read_crestereo_disp
|
||||
|
||||
|
||||
def _build_cache(self):
|
||||
allpairs = [s+'/'+f[:-len('_left.jpg')] for s in sorted(os.listdir(self.root)) for f in sorted(os.listdir(self.root+'/'+s)) if f.endswith('_left.jpg')]
|
||||
assert len(allpairs)==200000, "incorrect parsing of pairs in CreStereo"
|
||||
tosave = {'train': allpairs}
|
||||
return tosave
|
||||
|
||||
class SceneFlowDataset(StereoDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "SceneFlow"
|
||||
self._set_root()
|
||||
assert self.split in ['train_finalpass','train_cleanpass','train_allpass','test_finalpass','test_cleanpass','test_allpass','test1of100_cleanpass','test1of100_finalpass']
|
||||
self.pairname_to_Limgname = lambda pairname: osp.join(self.root, pairname)
|
||||
self.pairname_to_Rimgname = lambda pairname: osp.join(self.root, pairname).replace('/left/','/right/')
|
||||
self.pairname_to_Ldispname = lambda pairname: osp.join(self.root, pairname).replace('/frames_finalpass/','/disparity/').replace('/frames_cleanpass/','/disparity/')[:-4]+'.pfm'
|
||||
self.pairname_to_str = lambda pairname: pairname[:-4]
|
||||
self.load_disparity = _read_sceneflow_disp
|
||||
|
||||
def _build_cache(self):
|
||||
trainpairs = []
|
||||
# driving
|
||||
pairs = sorted(glob(self.root+'Driving/frames_finalpass/*/*/*/left/*.png'))
|
||||
pairs = list(map(lambda x: x[len(self.root):], pairs))
|
||||
assert len(pairs) == 4400, "incorrect parsing of pairs in SceneFlow"
|
||||
trainpairs += pairs
|
||||
# monkaa
|
||||
pairs = sorted(glob(self.root+'Monkaa/frames_finalpass/*/left/*.png'))
|
||||
pairs = list(map(lambda x: x[len(self.root):], pairs))
|
||||
assert len(pairs) == 8664, "incorrect parsing of pairs in SceneFlow"
|
||||
trainpairs += pairs
|
||||
# flyingthings
|
||||
pairs = sorted(glob(self.root+'FlyingThings/frames_finalpass/TRAIN/*/*/left/*.png'))
|
||||
pairs = list(map(lambda x: x[len(self.root):], pairs))
|
||||
assert len(pairs) == 22390, "incorrect parsing of pairs in SceneFlow"
|
||||
trainpairs += pairs
|
||||
assert len(trainpairs) == 35454, "incorrect parsing of pairs in SceneFlow"
|
||||
testpairs = sorted(glob(self.root+'FlyingThings/frames_finalpass/TEST/*/*/left/*.png'))
|
||||
testpairs = list(map(lambda x: x[len(self.root):], testpairs))
|
||||
assert len(testpairs) == 4370, "incorrect parsing of pairs in SceneFlow"
|
||||
test1of100pairs = testpairs[::100]
|
||||
assert len(test1of100pairs) == 44, "incorrect parsing of pairs in SceneFlow"
|
||||
# all
|
||||
tosave = {'train_finalpass': trainpairs,
|
||||
'train_cleanpass': list(map(lambda x: x.replace('frames_finalpass','frames_cleanpass'), trainpairs)),
|
||||
'test_finalpass': testpairs,
|
||||
'test_cleanpass': list(map(lambda x: x.replace('frames_finalpass','frames_cleanpass'), testpairs)),
|
||||
'test1of100_finalpass': test1of100pairs,
|
||||
'test1of100_cleanpass': list(map(lambda x: x.replace('frames_finalpass','frames_cleanpass'), test1of100pairs)),
|
||||
}
|
||||
tosave['train_allpass'] = tosave['train_finalpass']+tosave['train_cleanpass']
|
||||
tosave['test_allpass'] = tosave['test_finalpass']+tosave['test_cleanpass']
|
||||
return tosave
|
||||
|
||||
class Md21Dataset(StereoDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "Middlebury2021"
|
||||
self._set_root()
|
||||
assert self.split in ['train','subtrain','subval']
|
||||
self.pairname_to_Limgname = lambda pairname: osp.join(self.root, pairname)
|
||||
self.pairname_to_Rimgname = lambda pairname: osp.join(self.root, pairname.replace('/im0','/im1'))
|
||||
self.pairname_to_Ldispname = lambda pairname: osp.join(self.root, pairname.split('/')[0], 'disp0.pfm')
|
||||
self.pairname_to_str = lambda pairname: pairname[:-4]
|
||||
self.load_disparity = _read_middlebury_disp
|
||||
|
||||
def _build_cache(self):
|
||||
seqs = sorted(os.listdir(self.root))
|
||||
trainpairs = []
|
||||
for s in seqs:
|
||||
#trainpairs += [s+'/im0.png'] # we should remove it, it is included as such in other lightings
|
||||
trainpairs += [s+'/ambient/'+b+'/'+a for b in sorted(os.listdir(osp.join(self.root,s,'ambient'))) for a in sorted(os.listdir(osp.join(self.root,s,'ambient',b))) if a.startswith('im0')]
|
||||
assert len(trainpairs)==355
|
||||
subtrainpairs = [p for p in trainpairs if any(p.startswith(s+'/') for s in seqs[:-2])]
|
||||
subvalpairs = [p for p in trainpairs if any(p.startswith(s+'/') for s in seqs[-2:])]
|
||||
assert len(subtrainpairs)==335 and len(subvalpairs)==20, "incorrect parsing of pairs in Middlebury 2021"
|
||||
tosave = {'train': trainpairs, 'subtrain': subtrainpairs, 'subval': subvalpairs}
|
||||
return tosave
|
||||
|
||||
class Md14Dataset(StereoDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "Middlebury2014"
|
||||
self._set_root()
|
||||
assert self.split in ['train','subtrain','subval']
|
||||
self.pairname_to_Limgname = lambda pairname: osp.join(self.root, osp.dirname(pairname), 'im0.png')
|
||||
self.pairname_to_Rimgname = lambda pairname: osp.join(self.root, pairname)
|
||||
self.pairname_to_Ldispname = lambda pairname: osp.join(self.root, osp.dirname(pairname), 'disp0.pfm')
|
||||
self.pairname_to_str = lambda pairname: pairname[:-4]
|
||||
self.load_disparity = _read_middlebury_disp
|
||||
self.has_constant_resolution = False
|
||||
|
||||
def _build_cache(self):
|
||||
seqs = sorted(os.listdir(self.root))
|
||||
trainpairs = []
|
||||
for s in seqs:
|
||||
trainpairs += [s+'/im1.png',s+'/im1E.png',s+'/im1L.png']
|
||||
assert len(trainpairs)==138
|
||||
valseqs = ['Umbrella-imperfect','Vintage-perfect']
|
||||
assert all(s in seqs for s in valseqs)
|
||||
subtrainpairs = [p for p in trainpairs if not any(p.startswith(s+'/') for s in valseqs)]
|
||||
subvalpairs = [p for p in trainpairs if any(p.startswith(s+'/') for s in valseqs)]
|
||||
assert len(subtrainpairs)==132 and len(subvalpairs)==6, "incorrect parsing of pairs in Middlebury 2014"
|
||||
tosave = {'train': trainpairs, 'subtrain': subtrainpairs, 'subval': subvalpairs}
|
||||
return tosave
|
||||
|
||||
class Md06Dataset(StereoDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "Middlebury2006"
|
||||
self._set_root()
|
||||
assert self.split in ['train','subtrain','subval']
|
||||
self.pairname_to_Limgname = lambda pairname: osp.join(self.root, pairname)
|
||||
self.pairname_to_Rimgname = lambda pairname: osp.join(self.root, osp.dirname(pairname), 'view5.png')
|
||||
self.pairname_to_Ldispname = lambda pairname: osp.join(self.root, pairname.split('/')[0], 'disp1.png')
|
||||
self.load_disparity = _read_middlebury20052006_disp
|
||||
self.has_constant_resolution = False
|
||||
|
||||
def _build_cache(self):
|
||||
seqs = sorted(os.listdir(self.root))
|
||||
trainpairs = []
|
||||
for s in seqs:
|
||||
for i in ['Illum1','Illum2','Illum3']:
|
||||
for e in ['Exp0','Exp1','Exp2']:
|
||||
trainpairs.append(osp.join(s,i,e,'view1.png'))
|
||||
assert len(trainpairs)==189
|
||||
valseqs = ['Rocks1','Wood2']
|
||||
assert all(s in seqs for s in valseqs)
|
||||
subtrainpairs = [p for p in trainpairs if not any(p.startswith(s+'/') for s in valseqs)]
|
||||
subvalpairs = [p for p in trainpairs if any(p.startswith(s+'/') for s in valseqs)]
|
||||
assert len(subtrainpairs)==171 and len(subvalpairs)==18, "incorrect parsing of pairs in Middlebury 2006"
|
||||
tosave = {'train': trainpairs, 'subtrain': subtrainpairs, 'subval': subvalpairs}
|
||||
return tosave
|
||||
|
||||
class Md05Dataset(StereoDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "Middlebury2005"
|
||||
self._set_root()
|
||||
assert self.split in ['train','subtrain','subval']
|
||||
self.pairname_to_Limgname = lambda pairname: osp.join(self.root, pairname)
|
||||
self.pairname_to_Rimgname = lambda pairname: osp.join(self.root, osp.dirname(pairname), 'view5.png')
|
||||
self.pairname_to_Ldispname = lambda pairname: osp.join(self.root, pairname.split('/')[0], 'disp1.png')
|
||||
self.pairname_to_str = lambda pairname: pairname[:-4]
|
||||
self.load_disparity = _read_middlebury20052006_disp
|
||||
|
||||
def _build_cache(self):
|
||||
seqs = sorted(os.listdir(self.root))
|
||||
trainpairs = []
|
||||
for s in seqs:
|
||||
for i in ['Illum1','Illum2','Illum3']:
|
||||
for e in ['Exp0','Exp1','Exp2']:
|
||||
trainpairs.append(osp.join(s,i,e,'view1.png'))
|
||||
assert len(trainpairs)==54, "incorrect parsing of pairs in Middlebury 2005"
|
||||
valseqs = ['Reindeer']
|
||||
assert all(s in seqs for s in valseqs)
|
||||
subtrainpairs = [p for p in trainpairs if not any(p.startswith(s+'/') for s in valseqs)]
|
||||
subvalpairs = [p for p in trainpairs if any(p.startswith(s+'/') for s in valseqs)]
|
||||
assert len(subtrainpairs)==45 and len(subvalpairs)==9, "incorrect parsing of pairs in Middlebury 2005"
|
||||
tosave = {'train': trainpairs, 'subtrain': subtrainpairs, 'subval': subvalpairs}
|
||||
return tosave
|
||||
|
||||
class MdEval3Dataset(StereoDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "MiddleburyEval3"
|
||||
self._set_root()
|
||||
assert self.split in [s+'_'+r for s in ['train','subtrain','subval','test','all'] for r in ['full','half','quarter']]
|
||||
if self.split.endswith('_full'):
|
||||
self.root = self.root.replace('/MiddEval3','/MiddEval3_F')
|
||||
elif self.split.endswith('_half'):
|
||||
self.root = self.root.replace('/MiddEval3','/MiddEval3_H')
|
||||
else:
|
||||
assert self.split.endswith('_quarter')
|
||||
self.pairname_to_Limgname = lambda pairname: osp.join(self.root, pairname, 'im0.png')
|
||||
self.pairname_to_Rimgname = lambda pairname: osp.join(self.root, pairname, 'im1.png')
|
||||
self.pairname_to_Ldispname = lambda pairname: None if pairname.startswith('test') else osp.join(self.root, pairname, 'disp0GT.pfm')
|
||||
self.pairname_to_str = lambda pairname: pairname
|
||||
self.load_disparity = _read_middlebury_disp
|
||||
# for submission only
|
||||
self.submission_methodname = "CroCo-Stereo"
|
||||
self.submission_sresolution = 'F' if self.split.endswith('_full') else ('H' if self.split.endswith('_half') else 'Q')
|
||||
|
||||
def _build_cache(self):
|
||||
trainpairs = ['train/'+s for s in sorted(os.listdir(self.root+'train/'))]
|
||||
testpairs = ['test/'+s for s in sorted(os.listdir(self.root+'test/'))]
|
||||
subvalpairs = trainpairs[-1:]
|
||||
subtrainpairs = trainpairs[:-1]
|
||||
allpairs = trainpairs+testpairs
|
||||
assert len(trainpairs)==15 and len(testpairs)==15 and len(subvalpairs)==1 and len(subtrainpairs)==14 and len(allpairs)==30, "incorrect parsing of pairs in Middlebury Eval v3"
|
||||
tosave = {}
|
||||
for r in ['full','half','quarter']:
|
||||
tosave.update(**{'train_'+r: trainpairs, 'subtrain_'+r: subtrainpairs, 'subval_'+r: subvalpairs, 'test_'+r: testpairs, 'all_'+r: allpairs})
|
||||
return tosave
|
||||
|
||||
def submission_save_pairname(self, pairname, prediction, outdir, time):
|
||||
assert prediction.ndim==2
|
||||
assert prediction.dtype==np.float32
|
||||
outfile = os.path.join(outdir, pairname.split('/')[0].replace('train','training')+self.submission_sresolution, pairname.split('/')[1], 'disp0'+self.submission_methodname+'.pfm')
|
||||
os.makedirs( os.path.dirname(outfile), exist_ok=True)
|
||||
writePFM(outfile, prediction)
|
||||
timefile = os.path.join( os.path.dirname(outfile), "time"+self.submission_methodname+'.txt')
|
||||
with open(timefile, 'w') as fid:
|
||||
fid.write(str(time))
|
||||
|
||||
def finalize_submission(self, outdir):
|
||||
cmd = f'cd {outdir}/; zip -r "{self.submission_methodname}.zip" .'
|
||||
print(cmd)
|
||||
os.system(cmd)
|
||||
print(f'Done. Submission file at {outdir}/{self.submission_methodname}.zip')
|
||||
|
||||
class ETH3DLowResDataset(StereoDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "ETH3DLowRes"
|
||||
self._set_root()
|
||||
assert self.split in ['train','test','subtrain','subval','all']
|
||||
self.pairname_to_Limgname = lambda pairname: osp.join(self.root, pairname, 'im0.png')
|
||||
self.pairname_to_Rimgname = lambda pairname: osp.join(self.root, pairname, 'im1.png')
|
||||
self.pairname_to_Ldispname = None if self.split=='test' else lambda pairname: None if pairname.startswith('test/') else osp.join(self.root, pairname.replace('train/','train_gt/'), 'disp0GT.pfm')
|
||||
self.pairname_to_str = lambda pairname: pairname
|
||||
self.load_disparity = _read_eth3d_disp
|
||||
self.has_constant_resolution = False
|
||||
|
||||
def _build_cache(self):
|
||||
trainpairs = ['train/' + s for s in sorted(os.listdir(self.root+'train/'))]
|
||||
testpairs = ['test/' + s for s in sorted(os.listdir(self.root+'test/'))]
|
||||
assert len(trainpairs) == 27 and len(testpairs) == 20, "incorrect parsing of pairs in ETH3D Low Res"
|
||||
subvalpairs = ['train/delivery_area_3s','train/electro_3l','train/playground_3l']
|
||||
assert all(p in trainpairs for p in subvalpairs)
|
||||
subtrainpairs = [p for p in trainpairs if not p in subvalpairs]
|
||||
assert len(subvalpairs)==3 and len(subtrainpairs)==24, "incorrect parsing of pairs in ETH3D Low Res"
|
||||
tosave = {'train': trainpairs, 'test': testpairs, 'subtrain': subtrainpairs, 'subval': subvalpairs, 'all': trainpairs+testpairs}
|
||||
return tosave
|
||||
|
||||
def submission_save_pairname(self, pairname, prediction, outdir, time):
|
||||
assert prediction.ndim==2
|
||||
assert prediction.dtype==np.float32
|
||||
outfile = os.path.join(outdir, 'low_res_two_view', pairname.split('/')[1]+'.pfm')
|
||||
os.makedirs( os.path.dirname(outfile), exist_ok=True)
|
||||
writePFM(outfile, prediction)
|
||||
timefile = outfile[:-4]+'.txt'
|
||||
with open(timefile, 'w') as fid:
|
||||
fid.write('runtime '+str(time))
|
||||
|
||||
def finalize_submission(self, outdir):
|
||||
cmd = f'cd {outdir}/; zip -r "eth3d_low_res_two_view_results.zip" low_res_two_view'
|
||||
print(cmd)
|
||||
os.system(cmd)
|
||||
print(f'Done. Submission file at {outdir}/eth3d_low_res_two_view_results.zip')
|
||||
|
||||
class BoosterDataset(StereoDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "Booster"
|
||||
self._set_root()
|
||||
assert self.split in ['train_balanced','test_balanced','subtrain_balanced','subval_balanced'] # we use only the balanced version
|
||||
self.pairname_to_Limgname = lambda pairname: osp.join(self.root, pairname)
|
||||
self.pairname_to_Rimgname = lambda pairname: osp.join(self.root, pairname).replace('/camera_00/','/camera_02/')
|
||||
self.pairname_to_Ldispname = lambda pairname: osp.join(self.root, osp.dirname(pairname), '../disp_00.npy') # same images with different colors, same gt per sequence
|
||||
self.pairname_to_str = lambda pairname: pairname[:-4].replace('/camera_00/','/')
|
||||
self.load_disparity = _read_booster_disp
|
||||
|
||||
|
||||
def _build_cache(self):
|
||||
trainseqs = sorted(os.listdir(self.root+'train/balanced'))
|
||||
trainpairs = ['train/balanced/'+s+'/camera_00/'+imname for s in trainseqs for imname in sorted(os.listdir(self.root+'train/balanced/'+s+'/camera_00/'))]
|
||||
testpairs = ['test/balanced/'+s+'/camera_00/'+imname for s in sorted(os.listdir(self.root+'test/balanced')) for imname in sorted(os.listdir(self.root+'test/balanced/'+s+'/camera_00/'))]
|
||||
assert len(trainpairs) == 228 and len(testpairs) == 191
|
||||
subtrainpairs = [p for p in trainpairs if any(s in p for s in trainseqs[:-2])]
|
||||
subvalpairs = [p for p in trainpairs if any(s in p for s in trainseqs[-2:])]
|
||||
# warning: if we do validation split, we should split scenes!!!
|
||||
tosave = {'train_balanced': trainpairs, 'test_balanced': testpairs, 'subtrain_balanced': subtrainpairs, 'subval_balanced': subvalpairs,}
|
||||
return tosave
|
||||
|
||||
class SpringDataset(StereoDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "Spring"
|
||||
self._set_root()
|
||||
assert self.split in ['train', 'test', 'subtrain', 'subval']
|
||||
self.pairname_to_Limgname = lambda pairname: osp.join(self.root, pairname+'.png')
|
||||
self.pairname_to_Rimgname = lambda pairname: osp.join(self.root, pairname+'.png').replace('frame_right','<frame_right>').replace('frame_left','frame_right').replace('<frame_right>','frame_left')
|
||||
self.pairname_to_Ldispname = lambda pairname: None if pairname.startswith('test') else osp.join(self.root, pairname+'.dsp5').replace('frame_left','disp1_left').replace('frame_right','disp1_right')
|
||||
self.pairname_to_str = lambda pairname: pairname
|
||||
self.load_disparity = _read_hdf5_disp
|
||||
|
||||
def _build_cache(self):
|
||||
trainseqs = sorted(os.listdir( osp.join(self.root,'train')))
|
||||
trainpairs = [osp.join('train',s,'frame_left',f[:-4]) for s in trainseqs for f in sorted(os.listdir(osp.join(self.root,'train',s,'frame_left')))]
|
||||
testseqs = sorted(os.listdir( osp.join(self.root,'test')))
|
||||
testpairs = [osp.join('test',s,'frame_left',f[:-4]) for s in testseqs for f in sorted(os.listdir(osp.join(self.root,'test',s,'frame_left')))]
|
||||
testpairs += [p.replace('frame_left','frame_right') for p in testpairs]
|
||||
"""maxnorm = {'0001': 32.88, '0002': 228.5, '0004': 298.2, '0005': 142.5, '0006': 113.6, '0007': 27.3, '0008': 554.5, '0009': 155.6, '0010': 126.1, '0011': 87.6, '0012': 303.2, '0013': 24.14, '0014': 82.56, '0015': 98.44, '0016': 156.9, '0017': 28.17, '0018': 21.03, '0020': 178.0, '0021': 58.06, '0022': 354.2, '0023': 8.79, '0024': 97.06, '0025': 55.16, '0026': 91.9, '0027': 156.6, '0030': 200.4, '0032': 58.66, '0033': 373.5, '0036': 149.4, '0037': 5.625, '0038': 37.0, '0039': 12.2, '0041': 453.5, '0043': 457.0, '0044': 379.5, '0045': 161.8, '0047': 105.44} # => let'use 0041"""
|
||||
subtrainpairs = [p for p in trainpairs if p.split('/')[1]!='0041']
|
||||
subvalpairs = [p for p in trainpairs if p.split('/')[1]=='0041']
|
||||
assert len(trainpairs)==5000 and len(testpairs)==2000 and len(subtrainpairs)==4904 and len(subvalpairs)==96, "incorrect parsing of pairs in Spring"
|
||||
tosave = {'train': trainpairs, 'test': testpairs, 'subtrain': subtrainpairs, 'subval': subvalpairs}
|
||||
return tosave
|
||||
|
||||
def submission_save_pairname(self, pairname, prediction, outdir, time):
|
||||
assert prediction.ndim==2
|
||||
assert prediction.dtype==np.float32
|
||||
outfile = os.path.join(outdir, pairname+'.dsp5').replace('frame_left','disp1_left').replace('frame_right','disp1_right')
|
||||
os.makedirs( os.path.dirname(outfile), exist_ok=True)
|
||||
writeDsp5File(prediction, outfile)
|
||||
|
||||
def finalize_submission(self, outdir):
|
||||
assert self.split=='test'
|
||||
exe = "{self.root}/disp1_subsampling"
|
||||
if os.path.isfile(exe):
|
||||
cmd = f'cd "{outdir}/test"; {exe} .'
|
||||
print(cmd)
|
||||
os.system(cmd)
|
||||
else:
|
||||
print('Could not find disp1_subsampling executable for submission.')
|
||||
print('Please download it and run:')
|
||||
print(f'cd "{outdir}/test"; <disp1_subsampling_exe> .')
|
||||
|
||||
class Kitti12Dataset(StereoDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "Kitti12"
|
||||
self._set_root()
|
||||
assert self.split in ['train','test']
|
||||
self.pairname_to_Limgname = lambda pairname: osp.join(self.root, pairname+'_10.png')
|
||||
self.pairname_to_Rimgname = lambda pairname: osp.join(self.root, pairname.replace('/colored_0/','/colored_1/')+'_10.png')
|
||||
self.pairname_to_Ldispname = None if self.split=='test' else lambda pairname: osp.join(self.root, pairname.replace('/colored_0/','/disp_occ/')+'_10.png')
|
||||
self.pairname_to_str = lambda pairname: pairname.replace('/colored_0/','/')
|
||||
self.load_disparity = _read_kitti_disp
|
||||
|
||||
def _build_cache(self):
|
||||
trainseqs = ["training/colored_0/%06d"%(i) for i in range(194)]
|
||||
testseqs = ["testing/colored_0/%06d"%(i) for i in range(195)]
|
||||
assert len(trainseqs)==194 and len(testseqs)==195, "incorrect parsing of pairs in Kitti12"
|
||||
tosave = {'train': trainseqs, 'test': testseqs}
|
||||
return tosave
|
||||
|
||||
def submission_save_pairname(self, pairname, prediction, outdir, time):
|
||||
assert prediction.ndim==2
|
||||
assert prediction.dtype==np.float32
|
||||
outfile = os.path.join(outdir, pairname.split('/')[-1]+'_10.png')
|
||||
os.makedirs( os.path.dirname(outfile), exist_ok=True)
|
||||
img = (prediction * 256).astype('uint16')
|
||||
Image.fromarray(img).save(outfile)
|
||||
|
||||
def finalize_submission(self, outdir):
|
||||
assert self.split=='test'
|
||||
cmd = f'cd {outdir}/; zip -r "kitti12_results.zip" .'
|
||||
print(cmd)
|
||||
os.system(cmd)
|
||||
print(f'Done. Submission file at {outdir}/kitti12_results.zip')
|
||||
|
||||
class Kitti15Dataset(StereoDataset):
|
||||
|
||||
def _prepare_data(self):
|
||||
self.name = "Kitti15"
|
||||
self._set_root()
|
||||
assert self.split in ['train','subtrain','subval','test']
|
||||
self.pairname_to_Limgname = lambda pairname: osp.join(self.root, pairname+'_10.png')
|
||||
self.pairname_to_Rimgname = lambda pairname: osp.join(self.root, pairname.replace('/image_2/','/image_3/')+'_10.png')
|
||||
self.pairname_to_Ldispname = None if self.split=='test' else lambda pairname: osp.join(self.root, pairname.replace('/image_2/','/disp_occ_0/')+'_10.png')
|
||||
self.pairname_to_str = lambda pairname: pairname.replace('/image_2/','/')
|
||||
self.load_disparity = _read_kitti_disp
|
||||
|
||||
def _build_cache(self):
|
||||
trainseqs = ["training/image_2/%06d"%(i) for i in range(200)]
|
||||
subtrainseqs = trainseqs[:-5]
|
||||
subvalseqs = trainseqs[-5:]
|
||||
testseqs = ["testing/image_2/%06d"%(i) for i in range(200)]
|
||||
assert len(trainseqs)==200 and len(subtrainseqs)==195 and len(subvalseqs)==5 and len(testseqs)==200, "incorrect parsing of pairs in Kitti15"
|
||||
tosave = {'train': trainseqs, 'subtrain': subtrainseqs, 'subval': subvalseqs, 'test': testseqs}
|
||||
return tosave
|
||||
|
||||
def submission_save_pairname(self, pairname, prediction, outdir, time):
|
||||
assert prediction.ndim==2
|
||||
assert prediction.dtype==np.float32
|
||||
outfile = os.path.join(outdir, 'disp_0', pairname.split('/')[-1]+'_10.png')
|
||||
os.makedirs( os.path.dirname(outfile), exist_ok=True)
|
||||
img = (prediction * 256).astype('uint16')
|
||||
Image.fromarray(img).save(outfile)
|
||||
|
||||
def finalize_submission(self, outdir):
|
||||
assert self.split=='test'
|
||||
cmd = f'cd {outdir}/; zip -r "kitti15_results.zip" disp_0'
|
||||
print(cmd)
|
||||
os.system(cmd)
|
||||
print(f'Done. Submission file at {outdir}/kitti15_results.zip')
|
||||
|
||||
|
||||
### auxiliary functions
|
||||
|
||||
def _read_img(filename):
|
||||
# convert to RGB for scene flow finalpass data
|
||||
img = np.asarray(Image.open(filename).convert('RGB'))
|
||||
return img
|
||||
|
||||
def _read_booster_disp(filename):
|
||||
disp = np.load(filename)
|
||||
disp[disp==0.0] = np.inf
|
||||
return disp
|
||||
|
||||
def _read_png_disp(filename, coef=1.0):
|
||||
disp = np.asarray(Image.open(filename))
|
||||
disp = disp.astype(np.float32) / coef
|
||||
disp[disp==0.0] = np.inf
|
||||
return disp
|
||||
|
||||
def _read_pfm_disp(filename):
|
||||
disp = np.ascontiguousarray(_read_pfm(filename)[0])
|
||||
disp[disp<=0] = np.inf # eg /nfs/data/ffs-3d/datasets/middlebury/2014/Shopvac-imperfect/disp0.pfm
|
||||
return disp
|
||||
|
||||
def _read_npy_disp(filename):
|
||||
return np.load(filename)
|
||||
|
||||
def _read_crestereo_disp(filename): return _read_png_disp(filename, coef=32.0)
|
||||
def _read_middlebury20052006_disp(filename): return _read_png_disp(filename, coef=1.0)
|
||||
def _read_kitti_disp(filename): return _read_png_disp(filename, coef=256.0)
|
||||
_read_sceneflow_disp = _read_pfm_disp
|
||||
_read_eth3d_disp = _read_pfm_disp
|
||||
_read_middlebury_disp = _read_pfm_disp
|
||||
_read_carla_disp = _read_pfm_disp
|
||||
_read_tartanair_disp = _read_npy_disp
|
||||
|
||||
def _read_hdf5_disp(filename):
|
||||
disp = np.asarray(h5py.File(filename)['disparity'])
|
||||
disp[np.isnan(disp)] = np.inf # make invalid values as +inf
|
||||
#disp[disp==0.0] = np.inf # make invalid values as +inf
|
||||
return disp.astype(np.float32)
|
||||
|
||||
import re
|
||||
def _read_pfm(file):
|
||||
file = open(file, 'rb')
|
||||
|
||||
color = None
|
||||
width = None
|
||||
height = None
|
||||
scale = None
|
||||
endian = None
|
||||
|
||||
header = file.readline().rstrip()
|
||||
if header.decode("ascii") == 'PF':
|
||||
color = True
|
||||
elif header.decode("ascii") == 'Pf':
|
||||
color = False
|
||||
else:
|
||||
raise Exception('Not a PFM file.')
|
||||
|
||||
dim_match = re.match(r'^(\d+)\s(\d+)\s$', file.readline().decode("ascii"))
|
||||
if dim_match:
|
||||
width, height = list(map(int, dim_match.groups()))
|
||||
else:
|
||||
raise Exception('Malformed PFM header.')
|
||||
|
||||
scale = float(file.readline().decode("ascii").rstrip())
|
||||
if scale < 0: # little-endian
|
||||
endian = '<'
|
||||
scale = -scale
|
||||
else:
|
||||
endian = '>' # big-endian
|
||||
|
||||
data = np.fromfile(file, endian + 'f')
|
||||
shape = (height, width, 3) if color else (height, width)
|
||||
|
||||
data = np.reshape(data, shape)
|
||||
data = np.flipud(data)
|
||||
return data, scale
|
||||
|
||||
def writePFM(file, image, scale=1):
|
||||
file = open(file, 'wb')
|
||||
|
||||
color = None
|
||||
|
||||
if image.dtype.name != 'float32':
|
||||
raise Exception('Image dtype must be float32.')
|
||||
|
||||
image = np.flipud(image)
|
||||
|
||||
if len(image.shape) == 3 and image.shape[2] == 3: # color image
|
||||
color = True
|
||||
elif len(image.shape) == 2 or len(image.shape) == 3 and image.shape[2] == 1: # greyscale
|
||||
color = False
|
||||
else:
|
||||
raise Exception('Image must have H x W x 3, H x W x 1 or H x W dimensions.')
|
||||
|
||||
file.write('PF\n' if color else 'Pf\n'.encode())
|
||||
file.write('%d %d\n'.encode() % (image.shape[1], image.shape[0]))
|
||||
|
||||
endian = image.dtype.byteorder
|
||||
|
||||
if endian == '<' or endian == '=' and sys.byteorder == 'little':
|
||||
scale = -scale
|
||||
|
||||
file.write('%f\n'.encode() % scale)
|
||||
|
||||
image.tofile(file)
|
||||
|
||||
def writeDsp5File(disp, filename):
|
||||
with h5py.File(filename, "w") as f:
|
||||
f.create_dataset("disparity", data=disp, compression="gzip", compression_opts=5)
|
||||
|
||||
|
||||
# disp visualization
|
||||
|
||||
def vis_disparity(disp, m=None, M=None):
|
||||
if m is None: m = disp.min()
|
||||
if M is None: M = disp.max()
|
||||
disp_vis = (disp - m) / (M-m) * 255.0
|
||||
disp_vis = disp_vis.astype("uint8")
|
||||
disp_vis = cv2.applyColorMap(disp_vis, cv2.COLORMAP_INFERNO)
|
||||
return disp_vis
|
||||
|
||||
# dataset getter
|
||||
|
||||
def get_train_dataset_stereo(dataset_str, augmentor=True, crop_size=None):
|
||||
dataset_str = dataset_str.replace('(','Dataset(')
|
||||
if augmentor:
|
||||
dataset_str = dataset_str.replace(')',', augmentor=True)')
|
||||
if crop_size is not None:
|
||||
dataset_str = dataset_str.replace(')',', crop_size={:s})'.format(str(crop_size)))
|
||||
return eval(dataset_str)
|
||||
|
||||
def get_test_datasets_stereo(dataset_str):
|
||||
dataset_str = dataset_str.replace('(','Dataset(')
|
||||
return [eval(s) for s in dataset_str.split('+')]
|
||||
@@ -0,0 +1,12 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
model=$1
|
||||
outfile="stereoflow_models/${model}"
|
||||
if [[ ! -f $outfile ]]
|
||||
then
|
||||
mkdir -p stereoflow_models/;
|
||||
wget https://download.europe.naverlabs.com/ComputerVision/CroCo/StereoFlow_models/$1 -P stereoflow_models/;
|
||||
else
|
||||
echo "Model ${model} already downloaded in ${outfile}."
|
||||
fi
|
||||
@@ -0,0 +1,280 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
# --------------------------------------------------------
|
||||
# Main function for training one epoch or testing
|
||||
# --------------------------------------------------------
|
||||
|
||||
import math
|
||||
import sys
|
||||
from typing import Iterable
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchvision
|
||||
|
||||
from utils import misc as misc
|
||||
|
||||
|
||||
def split_prediction_conf(predictions, with_conf=False):
|
||||
if not with_conf:
|
||||
return predictions, None
|
||||
conf = predictions[:,-1:,:,:]
|
||||
predictions = predictions[:,:-1,:,:]
|
||||
return predictions, conf
|
||||
|
||||
def train_one_epoch(model: torch.nn.Module, criterion: torch.nn.Module, metrics: torch.nn.Module,
|
||||
data_loader: Iterable, optimizer: torch.optim.Optimizer,
|
||||
device: torch.device, epoch: int, loss_scaler,
|
||||
log_writer=None, print_freq = 20,
|
||||
args=None):
|
||||
model.train(True)
|
||||
metric_logger = misc.MetricLogger(delimiter=" ")
|
||||
metric_logger.add_meter('lr', misc.SmoothedValue(window_size=1, fmt='{value:.6f}'))
|
||||
header = 'Epoch: [{}]'.format(epoch)
|
||||
|
||||
accum_iter = args.accum_iter
|
||||
|
||||
optimizer.zero_grad()
|
||||
|
||||
details = {}
|
||||
|
||||
if log_writer is not None:
|
||||
print('log_dir: {}'.format(log_writer.log_dir))
|
||||
|
||||
if args.img_per_epoch:
|
||||
iter_per_epoch = args.img_per_epoch // args.batch_size + int(args.img_per_epoch % args.batch_size > 0)
|
||||
assert len(data_loader) >= iter_per_epoch, 'Dataset is too small for so many iterations'
|
||||
len_data_loader = iter_per_epoch
|
||||
else:
|
||||
len_data_loader, iter_per_epoch = len(data_loader), None
|
||||
|
||||
for data_iter_step, (image1, image2, gt, pairname) in enumerate(metric_logger.log_every(data_loader, print_freq, header, max_iter=iter_per_epoch)):
|
||||
|
||||
image1 = image1.to(device, non_blocking=True)
|
||||
image2 = image2.to(device, non_blocking=True)
|
||||
gt = gt.to(device, non_blocking=True)
|
||||
|
||||
# we use a per iteration (instead of per epoch) lr scheduler
|
||||
if data_iter_step % accum_iter == 0:
|
||||
misc.adjust_learning_rate(optimizer, data_iter_step / len_data_loader + epoch, args)
|
||||
|
||||
with torch.cuda.amp.autocast(enabled=bool(args.amp)):
|
||||
prediction = model(image1, image2)
|
||||
prediction, conf = split_prediction_conf(prediction, criterion.with_conf)
|
||||
batch_metrics = metrics(prediction.detach(), gt)
|
||||
loss = criterion(prediction, gt) if conf is None else criterion(prediction, gt, conf)
|
||||
|
||||
loss_value = loss.item()
|
||||
if not math.isfinite(loss_value):
|
||||
print("Loss is {}, stopping training".format(loss_value))
|
||||
sys.exit(1)
|
||||
|
||||
loss /= accum_iter
|
||||
loss_scaler(loss, optimizer, parameters=model.parameters(),
|
||||
update_grad=(data_iter_step + 1) % accum_iter == 0)
|
||||
if (data_iter_step + 1) % accum_iter == 0:
|
||||
optimizer.zero_grad()
|
||||
|
||||
torch.cuda.synchronize()
|
||||
|
||||
metric_logger.update(loss=loss_value)
|
||||
for k,v in batch_metrics.items():
|
||||
metric_logger.update(**{k: v.item()})
|
||||
lr = optimizer.param_groups[0]["lr"]
|
||||
metric_logger.update(lr=lr)
|
||||
|
||||
#if args.dsitributed: loss_value_reduce = misc.all_reduce_mean(loss_value)
|
||||
time_to_log = ((data_iter_step + 1) % (args.tboard_log_step * accum_iter) == 0 or data_iter_step == len_data_loader-1)
|
||||
loss_value_reduce = misc.all_reduce_mean(loss_value)
|
||||
if log_writer is not None and time_to_log:
|
||||
epoch_1000x = int((data_iter_step / len_data_loader + epoch) * 1000)
|
||||
# We use epoch_1000x as the x-axis in tensorboard. This calibrates different curves when batch size changes.
|
||||
log_writer.add_scalar('train/loss', loss_value_reduce, epoch_1000x)
|
||||
log_writer.add_scalar('lr', lr, epoch_1000x)
|
||||
for k,v in batch_metrics.items():
|
||||
log_writer.add_scalar('train/'+k, v.item(), epoch_1000x)
|
||||
|
||||
# gather the stats from all processes
|
||||
#if args.distributed: metric_logger.synchronize_between_processes()
|
||||
print("Averaged stats:", metric_logger)
|
||||
return {k: meter.global_avg for k, meter in metric_logger.meters.items()}
|
||||
|
||||
|
||||
@torch.no_grad()
|
||||
def validate_one_epoch(model: torch.nn.Module,
|
||||
criterion: torch.nn.Module,
|
||||
metrics: torch.nn.Module,
|
||||
data_loaders: list[Iterable],
|
||||
device: torch.device,
|
||||
epoch: int,
|
||||
log_writer=None,
|
||||
args=None):
|
||||
|
||||
model.eval()
|
||||
metric_loggers = []
|
||||
header = 'Epoch: [{}]'.format(epoch)
|
||||
print_freq = 20
|
||||
|
||||
conf_mode = args.tile_conf_mode
|
||||
crop = args.crop
|
||||
|
||||
if log_writer is not None:
|
||||
print('log_dir: {}'.format(log_writer.log_dir))
|
||||
|
||||
results = {}
|
||||
dnames = []
|
||||
image1, image2, gt, prediction = None, None, None, None
|
||||
for didx, data_loader in enumerate(data_loaders):
|
||||
dname = str(data_loader.dataset)
|
||||
dnames.append(dname)
|
||||
metric_loggers.append(misc.MetricLogger(delimiter=" "))
|
||||
for data_iter_step, (image1, image2, gt, pairname) in enumerate(metric_loggers[didx].log_every(data_loader, print_freq, header)):
|
||||
image1 = image1.to(device, non_blocking=True)
|
||||
image2 = image2.to(device, non_blocking=True)
|
||||
gt = gt.to(device, non_blocking=True)
|
||||
if dname.startswith('Spring'):
|
||||
assert gt.size(2)==image1.size(2)*2 and gt.size(3)==image1.size(3)*2
|
||||
gt = (gt[:,:,0::2,0::2] + gt[:,:,0::2,1::2] + gt[:,:,1::2,0::2] + gt[:,:,1::2,1::2] ) / 4.0 # we approximate the gt based on the 2x upsampled ones
|
||||
|
||||
with torch.inference_mode():
|
||||
prediction, tiled_loss, c = tiled_pred(model, criterion, image1, image2, gt, conf_mode=conf_mode, overlap=args.val_overlap, crop=crop, with_conf=criterion.with_conf)
|
||||
batch_metrics = metrics(prediction.detach(), gt)
|
||||
loss = criterion(prediction.detach(), gt) if not criterion.with_conf else criterion(prediction.detach(), gt, c)
|
||||
loss_value = loss.item()
|
||||
metric_loggers[didx].update(loss_tiled=tiled_loss.item())
|
||||
metric_loggers[didx].update(**{f'loss': loss_value})
|
||||
for k,v in batch_metrics.items():
|
||||
metric_loggers[didx].update(**{dname+'_' + k: v.item()})
|
||||
|
||||
results = {k: meter.global_avg for ml in metric_loggers for k, meter in ml.meters.items()}
|
||||
if len(dnames)>1:
|
||||
for k in batch_metrics.keys():
|
||||
results['AVG_'+k] = sum(results[dname+'_'+k] for dname in dnames) / len(dnames)
|
||||
|
||||
if log_writer is not None :
|
||||
epoch_1000x = int((1 + epoch) * 1000)
|
||||
for k,v in results.items():
|
||||
log_writer.add_scalar('val/'+k, v, epoch_1000x)
|
||||
|
||||
print("Averaged stats:", results)
|
||||
return results
|
||||
|
||||
import torch.nn.functional as F
|
||||
def _resize_img(img, new_size):
|
||||
return F.interpolate(img, size=new_size, mode='bicubic', align_corners=False)
|
||||
def _resize_stereo_or_flow(data, new_size):
|
||||
assert data.ndim==4
|
||||
assert data.size(1) in [1,2]
|
||||
scale_x = new_size[1]/float(data.size(3))
|
||||
out = F.interpolate(data, size=new_size, mode='bicubic', align_corners=False)
|
||||
out[:,0,:,:] *= scale_x
|
||||
if out.size(1)==2:
|
||||
scale_y = new_size[0]/float(data.size(2))
|
||||
out[:,1,:,:] *= scale_y
|
||||
print(scale_x, new_size, data.shape)
|
||||
return out
|
||||
|
||||
|
||||
@torch.no_grad()
|
||||
def tiled_pred(model, criterion, img1, img2, gt,
|
||||
overlap=0.5, bad_crop_thr=0.05,
|
||||
downscale=False, crop=512, ret='loss',
|
||||
conf_mode='conf_expsigmoid_10_5', with_conf=False,
|
||||
return_time=False):
|
||||
|
||||
# for each image, we are going to run inference on many overlapping patches
|
||||
# then, all predictions will be weighted-averaged
|
||||
if gt is not None:
|
||||
B, C, H, W = gt.shape
|
||||
else:
|
||||
B, _, H, W = img1.shape
|
||||
C = model.head.num_channels-int(with_conf)
|
||||
win_height, win_width = crop[0], crop[1]
|
||||
|
||||
# upscale to be larger than the crop
|
||||
do_change_scale = H<win_height or W<win_width
|
||||
if do_change_scale:
|
||||
upscale_factor = max(win_width/W, win_height/W)
|
||||
original_size = (H,W)
|
||||
new_size = (round(H*upscale_factor),round(W*upscale_factor))
|
||||
img1 = _resize_img(img1, new_size)
|
||||
img2 = _resize_img(img2, new_size)
|
||||
# resize gt just for the computation of tiled losses
|
||||
if gt is not None: gt = _resize_stereo_or_flow(gt, new_size)
|
||||
H,W = img1.shape[2:4]
|
||||
|
||||
if conf_mode.startswith('conf_expsigmoid_'): # conf_expsigmoid_30_10
|
||||
beta, betasigmoid = map(float, conf_mode[len('conf_expsigmoid_'):].split('_'))
|
||||
elif conf_mode.startswith('conf_expbeta'): # conf_expbeta3
|
||||
beta = float(conf_mode[len('conf_expbeta'):])
|
||||
else:
|
||||
raise NotImplementedError(f"conf_mode {conf_mode} is not implemented")
|
||||
|
||||
def crop_generator():
|
||||
for sy in _overlapping(H, win_height, overlap):
|
||||
for sx in _overlapping(W, win_width, overlap):
|
||||
yield sy, sx, sy, sx, True
|
||||
|
||||
# keep track of weighted sum of prediction*weights and weights
|
||||
accu_pred = img1.new_zeros((B, C, H, W)) # accumulate the weighted sum of predictions
|
||||
accu_conf = img1.new_zeros((B, H, W)) + 1e-16 # accumulate the weights
|
||||
accu_c = img1.new_zeros((B, H, W)) # accumulate the weighted sum of confidences ; not so useful except for computing some losses
|
||||
|
||||
tiled_losses = []
|
||||
|
||||
if return_time:
|
||||
start = torch.cuda.Event(enable_timing=True)
|
||||
end = torch.cuda.Event(enable_timing=True)
|
||||
start.record()
|
||||
|
||||
for sy1, sx1, sy2, sx2, aligned in crop_generator():
|
||||
# compute optical flow there
|
||||
pred = model(_crop(img1,sy1,sx1), _crop(img2,sy2,sx2))
|
||||
pred, predconf = split_prediction_conf(pred, with_conf=with_conf)
|
||||
|
||||
if gt is not None: gtcrop = _crop(gt,sy1,sx1)
|
||||
if criterion is not None and gt is not None:
|
||||
tiled_losses.append( criterion(pred, gtcrop).item() if predconf is None else criterion(pred, gtcrop, predconf).item() )
|
||||
|
||||
if conf_mode.startswith('conf_expsigmoid_'):
|
||||
conf = torch.exp(- beta * 2 * (torch.sigmoid(predconf / betasigmoid) - 0.5)).view(B,win_height,win_width)
|
||||
elif conf_mode.startswith('conf_expbeta'):
|
||||
conf = torch.exp(- beta * predconf).view(B,win_height,win_width)
|
||||
else:
|
||||
raise NotImplementedError
|
||||
|
||||
accu_pred[...,sy1,sx1] += pred * conf[:,None,:,:]
|
||||
accu_conf[...,sy1,sx1] += conf
|
||||
accu_c[...,sy1,sx1] += predconf.view(B,win_height,win_width) * conf
|
||||
|
||||
pred = accu_pred / accu_conf[:, None,:,:]
|
||||
c = accu_c / accu_conf
|
||||
assert not torch.any(torch.isnan(pred))
|
||||
|
||||
if return_time:
|
||||
end.record()
|
||||
torch.cuda.synchronize()
|
||||
time = start.elapsed_time(end)/1000.0 # this was in milliseconds
|
||||
|
||||
if do_change_scale:
|
||||
pred = _resize_stereo_or_flow(pred, original_size)
|
||||
|
||||
if return_time:
|
||||
return pred, torch.mean(torch.tensor(tiled_losses)), c, time
|
||||
return pred, torch.mean(torch.tensor(tiled_losses)), c
|
||||
|
||||
|
||||
def _overlapping(total, window, overlap=0.5):
|
||||
assert total >= window and 0 <= overlap < 1, (total, window, overlap)
|
||||
num_windows = 1 + int(np.ceil( (total - window) / ((1-overlap) * window) ))
|
||||
offsets = np.linspace(0, total-window, num_windows).round().astype(int)
|
||||
yield from (slice(x, x+window) for x in offsets)
|
||||
|
||||
def _crop(img, sy, sx):
|
||||
B, THREE, H, W = img.shape
|
||||
if 0 <= sy.start and sy.stop <= H and 0 <= sx.start and sx.stop <= W:
|
||||
return img[:,:,sy,sx]
|
||||
l, r = max(0,-sx.start), max(0,sx.stop-W)
|
||||
t, b = max(0,-sy.start), max(0,sy.stop-H)
|
||||
img = torch.nn.functional.pad(img, (l,r,t,b), mode='constant')
|
||||
return img[:, :, slice(sy.start+t,sy.stop+t), slice(sx.start+l,sx.stop+l)]
|
||||
+216
@@ -0,0 +1,216 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
# --------------------------------------------------------
|
||||
# Main test function
|
||||
# --------------------------------------------------------
|
||||
|
||||
import os
|
||||
import argparse
|
||||
import pickle
|
||||
from PIL import Image
|
||||
import numpy as np
|
||||
from tqdm import tqdm
|
||||
|
||||
import torch
|
||||
from torch.utils.data import DataLoader
|
||||
|
||||
import utils.misc as misc
|
||||
from models.croco_downstream import CroCoDownstreamBinocular
|
||||
from models.head_downstream import PixelwiseTaskWithDPT
|
||||
|
||||
from stereoflow.criterion import *
|
||||
from stereoflow.datasets_stereo import get_test_datasets_stereo
|
||||
from stereoflow.datasets_flow import get_test_datasets_flow
|
||||
from stereoflow.engine import tiled_pred
|
||||
|
||||
from stereoflow.datasets_stereo import vis_disparity
|
||||
from stereoflow.datasets_flow import flowToColor
|
||||
|
||||
def get_args_parser():
|
||||
parser = argparse.ArgumentParser('Test CroCo models on stereo/flow', add_help=False)
|
||||
# important argument
|
||||
parser.add_argument('--model', required=True, type=str, help='Path to the model to evaluate')
|
||||
parser.add_argument('--dataset', required=True, type=str, help="test dataset (there can be multiple dataset separated by a +)")
|
||||
# tiling
|
||||
parser.add_argument('--tile_conf_mode', type=str, default='', help='Weights for the tiling aggregation based on confidence (empty means use the formula from the loaded checkpoint')
|
||||
parser.add_argument('--tile_overlap', type=float, default=0.7, help='overlap between tiles')
|
||||
# save (it will automatically go to <model_path>_<dataset_str>/<tile_str>_<save>)
|
||||
parser.add_argument('--save', type=str, nargs='+', default=[],
|
||||
help='what to save: \
|
||||
metrics (pickle file), \
|
||||
pred (raw prediction save as torch tensor), \
|
||||
visu (visualization in png of each prediction), \
|
||||
err10 (visualization in png of the error clamp at 10 for each prediction), \
|
||||
submission (submission file)')
|
||||
# other (no impact)
|
||||
parser.add_argument('--num_workers', default=4, type=int)
|
||||
return parser
|
||||
|
||||
|
||||
def _load_model_and_criterion(model_path, do_load_metrics, device):
|
||||
print('loading model from', model_path)
|
||||
assert os.path.isfile(model_path)
|
||||
ckpt = torch.load(model_path, 'cpu')
|
||||
|
||||
ckpt_args = ckpt['args']
|
||||
task = ckpt_args.task
|
||||
tile_conf_mode = ckpt_args.tile_conf_mode
|
||||
num_channels = {'stereo': 1, 'flow': 2}[task]
|
||||
with_conf = eval(ckpt_args.criterion).with_conf
|
||||
if with_conf: num_channels += 1
|
||||
print('head: PixelwiseTaskWithDPT()')
|
||||
head = PixelwiseTaskWithDPT()
|
||||
head.num_channels = num_channels
|
||||
print('croco_args:', ckpt_args.croco_args)
|
||||
model = CroCoDownstreamBinocular(head, **ckpt_args.croco_args)
|
||||
msg = model.load_state_dict(ckpt['model'], strict=True)
|
||||
model.eval()
|
||||
model = model.to(device)
|
||||
|
||||
if do_load_metrics:
|
||||
if task=='stereo':
|
||||
metrics = StereoDatasetMetrics().to(device)
|
||||
else:
|
||||
metrics = FlowDatasetMetrics().to(device)
|
||||
else:
|
||||
metrics = None
|
||||
|
||||
return model, metrics, ckpt_args.crop, with_conf, task, tile_conf_mode
|
||||
|
||||
|
||||
def _save_batch(pred, gt, pairnames, dataset, task, save, outdir, time, submission_dir=None):
|
||||
|
||||
for i in range(len(pairnames)):
|
||||
|
||||
pairname = eval(pairnames[i]) if pairnames[i].startswith('(') else pairnames[i] # unbatch pairname
|
||||
fname = os.path.join(outdir, dataset.pairname_to_str(pairname))
|
||||
os.makedirs(os.path.dirname(fname), exist_ok=True)
|
||||
|
||||
predi = pred[i,...]
|
||||
if gt is not None: gti = gt[i,...]
|
||||
|
||||
if 'pred' in save:
|
||||
torch.save(predi.squeeze(0).cpu(), fname+'_pred.pth')
|
||||
|
||||
if 'visu' in save:
|
||||
if task=='stereo':
|
||||
disparity = predi.permute((1,2,0)).squeeze(2).cpu().numpy()
|
||||
m,M = None
|
||||
if gt is not None:
|
||||
mask = torch.isfinite(gti)
|
||||
m = gt[mask].min()
|
||||
M = gt[mask].max()
|
||||
img_disparity = vis_disparity(disparity, m=m, M=M)
|
||||
Image.fromarray(img_disparity).save(fname+'_pred.png')
|
||||
else:
|
||||
# normalize flowToColor according to the maxnorm of gt (or prediction if not available)
|
||||
flowNorm = torch.sqrt(torch.sum( (gti if gt is not None else predi)**2, dim=0)).max().item()
|
||||
imgflow = flowToColor(predi.permute((1,2,0)).cpu().numpy(), maxflow=flowNorm)
|
||||
Image.fromarray(imgflow).save(fname+'_pred.png')
|
||||
|
||||
if 'err10' in save:
|
||||
assert gt is not None
|
||||
L2err = torch.sqrt(torch.sum( (gti-predi)**2, dim=0))
|
||||
valid = torch.isfinite(gti[0,:,:])
|
||||
L2err[~valid] = 0.0
|
||||
L2err = torch.clamp(L2err, max=10.0)
|
||||
red = (L2err*255.0/10.0).to(dtype=torch.uint8)[:,:,None]
|
||||
zer = torch.zeros_like(red)
|
||||
imgerr = torch.cat( (red,zer,zer), dim=2).cpu().numpy()
|
||||
Image.fromarray(imgerr).save(fname+'_err10.png')
|
||||
|
||||
if 'submission' in save:
|
||||
assert submission_dir is not None
|
||||
predi_np = predi.permute(1,2,0).squeeze(2).cpu().numpy() # transform into HxWx2 for flow or HxW for stereo
|
||||
dataset.submission_save_pairname(pairname, predi_np, submission_dir, time)
|
||||
|
||||
def main(args):
|
||||
|
||||
# load the pretrained model and metrics
|
||||
device = torch.device('cuda:0') if torch.cuda.is_available() else torch.device('cpu')
|
||||
model, metrics, cropsize, with_conf, task, tile_conf_mode = _load_model_and_criterion(args.model, 'metrics' in args.save, device)
|
||||
if args.tile_conf_mode=='': args.tile_conf_mode = tile_conf_mode
|
||||
|
||||
# load the datasets
|
||||
datasets = (get_test_datasets_stereo if task=='stereo' else get_test_datasets_flow)(args.dataset)
|
||||
dataloaders = [DataLoader(dataset, batch_size=1, shuffle=False, num_workers=args.num_workers, pin_memory=True, drop_last=False) for dataset in datasets]
|
||||
|
||||
# run
|
||||
for i,dataloader in enumerate(dataloaders):
|
||||
dataset = datasets[i]
|
||||
dstr = args.dataset.split('+')[i]
|
||||
|
||||
outdir = args.model+'_'+misc.filename(dstr)
|
||||
if 'metrics' in args.save and len(args.save)==1:
|
||||
fname = os.path.join(outdir, f'conf_{args.tile_conf_mode}_overlap_{args.tile_overlap}.pkl')
|
||||
if os.path.isfile(fname) and len(args.save)==1:
|
||||
print(' metrics already compute in '+fname)
|
||||
with open(fname, 'rb') as fid:
|
||||
results = pickle.load(fid)
|
||||
for k,v in results.items():
|
||||
print('{:s}: {:.3f}'.format(k, v))
|
||||
continue
|
||||
|
||||
if 'submission' in args.save:
|
||||
dirname = f'submission_conf_{args.tile_conf_mode}_overlap_{args.tile_overlap}'
|
||||
submission_dir = os.path.join(outdir, dirname)
|
||||
else:
|
||||
submission_dir = None
|
||||
|
||||
print('')
|
||||
print('saving {:s} in {:s}'.format('+'.join(args.save), outdir))
|
||||
print(repr(dataset))
|
||||
|
||||
if metrics is not None:
|
||||
metrics.reset()
|
||||
|
||||
for data_iter_step, (image1, image2, gt, pairnames) in enumerate(tqdm(dataloader)):
|
||||
|
||||
do_flip = (task=='stereo' and dstr.startswith('Spring') and any("right" in p for p in pairnames)) # we flip the images and will flip the prediction after as we assume img1 is on the left
|
||||
|
||||
image1 = image1.to(device, non_blocking=True)
|
||||
image2 = image2.to(device, non_blocking=True)
|
||||
gt = gt.to(device, non_blocking=True) if gt.numel()>0 else None # special case for test time
|
||||
if do_flip:
|
||||
assert all("right" in p for p in pairnames)
|
||||
image1 = image1.flip(dims=[3]) # this is already the right frame, let's flip it
|
||||
image2 = image2.flip(dims=[3])
|
||||
gt = gt # that is ok
|
||||
|
||||
with torch.inference_mode():
|
||||
pred, _, _, time = tiled_pred(model, None, image1, image2, None if dataset.name=='Spring' else gt, conf_mode=args.tile_conf_mode, overlap=args.tile_overlap, crop=cropsize, with_conf=with_conf, return_time=True)
|
||||
|
||||
if do_flip:
|
||||
pred = pred.flip(dims=[3])
|
||||
|
||||
if metrics is not None:
|
||||
metrics.add_batch(pred, gt)
|
||||
|
||||
if any(k in args.save for k in ['pred','visu','err10','submission']):
|
||||
_save_batch(pred, gt, pairnames, dataset, task, args.save, outdir, time, submission_dir=submission_dir)
|
||||
|
||||
|
||||
# print
|
||||
if metrics is not None:
|
||||
results = metrics.get_results()
|
||||
for k,v in results.items():
|
||||
print('{:s}: {:.3f}'.format(k, v))
|
||||
|
||||
# save if needed
|
||||
if 'metrics' in args.save:
|
||||
os.makedirs(os.path.dirname(fname), exist_ok=True)
|
||||
with open(fname, 'wb') as fid:
|
||||
pickle.dump(results, fid)
|
||||
print('metrics saved in', fname)
|
||||
|
||||
# finalize submission if needed
|
||||
if 'submission' in args.save:
|
||||
dataset.finalize_submission(submission_dir)
|
||||
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
args = get_args_parser()
|
||||
args = args.parse_args()
|
||||
main(args)
|
||||
+253
@@ -0,0 +1,253 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
|
||||
# --------------------------------------------------------
|
||||
# Main training function
|
||||
# --------------------------------------------------------
|
||||
|
||||
import argparse
|
||||
import datetime
|
||||
import json
|
||||
import numpy as np
|
||||
import os
|
||||
import sys
|
||||
import time
|
||||
|
||||
import torch
|
||||
import torch.distributed as dist
|
||||
import torch.backends.cudnn as cudnn
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
import torchvision.transforms as transforms
|
||||
import torchvision.datasets as datasets
|
||||
from torch.utils.data import DataLoader
|
||||
|
||||
import utils
|
||||
import utils.misc as misc
|
||||
from utils.misc import NativeScalerWithGradNormCount as NativeScaler
|
||||
from models.croco_downstream import CroCoDownstreamBinocular, croco_args_from_ckpt
|
||||
from models.pos_embed import interpolate_pos_embed
|
||||
from models.head_downstream import PixelwiseTaskWithDPT
|
||||
|
||||
from stereoflow.datasets_stereo import get_train_dataset_stereo, get_test_datasets_stereo
|
||||
from stereoflow.datasets_flow import get_train_dataset_flow, get_test_datasets_flow
|
||||
from stereoflow.engine import train_one_epoch, validate_one_epoch
|
||||
from stereoflow.criterion import *
|
||||
|
||||
|
||||
def get_args_parser():
|
||||
# prepare subparsers
|
||||
parser = argparse.ArgumentParser('Finetuning CroCo models on stereo or flow', add_help=False)
|
||||
subparsers = parser.add_subparsers(title="Task (stereo or flow)", dest="task", required=True)
|
||||
parser_stereo = subparsers.add_parser('stereo', help='Training stereo model')
|
||||
parser_flow = subparsers.add_parser('flow', help='Training flow model')
|
||||
def add_arg(name_or_flags, default=None, default_stereo=None, default_flow=None, **kwargs):
|
||||
if default is not None: assert default_stereo is None and default_flow is None, "setting default makes default_stereo and default_flow disabled"
|
||||
parser_stereo.add_argument(name_or_flags, default=default if default is not None else default_stereo, **kwargs)
|
||||
parser_flow.add_argument(name_or_flags, default=default if default is not None else default_flow, **kwargs)
|
||||
# output dir
|
||||
add_arg('--output_dir', required=True, type=str, help='path where to save, if empty, automatically created')
|
||||
# model
|
||||
add_arg('--crop', type=int, nargs = '+', default_stereo=[352, 704], default_flow=[320, 384], help = "size of the random image crops used during training.")
|
||||
add_arg('--pretrained', required=True, type=str, help="Load pretrained model (required as croco arguments come from there)")
|
||||
# criterion
|
||||
add_arg('--criterion', default_stereo='LaplacianLossBounded2()', default_flow='LaplacianLossBounded()', type=str, help='string to evaluate to get criterion')
|
||||
add_arg('--bestmetric', default_stereo='avgerr', default_flow='EPE', type=str)
|
||||
# dataset
|
||||
add_arg('--dataset', type=str, required=True, help="training set")
|
||||
# training
|
||||
add_arg('--seed', default=0, type=int, help='seed')
|
||||
add_arg('--batch_size', default_stereo=6, default_flow=8, type=int, help='Batch size per GPU (effective batch size is batch_size * accum_iter * # gpus')
|
||||
add_arg('--epochs', default=32, type=int, help='number of training epochs')
|
||||
add_arg('--img_per_epoch', type=int, default=None, help='Fix the number of images seen in an epoch (None means use all training pairs)')
|
||||
add_arg('--accum_iter', default=1, type=int, help='Accumulate gradient iterations (for increasing the effective batch size under memory constraints)')
|
||||
add_arg('--weight_decay', type=float, default=0.05, help='weight decay (default: 0.05)')
|
||||
add_arg('--lr', type=float, default_stereo=3e-5, default_flow=2e-5, metavar='LR', help='learning rate (absolute lr)')
|
||||
add_arg('--min_lr', type=float, default=0., metavar='LR', help='lower lr bound for cyclic schedulers that hit 0')
|
||||
add_arg('--warmup_epochs', type=int, default=1, metavar='N', help='epochs to warmup LR')
|
||||
add_arg('--optimizer', default='AdamW(param_groups, lr=args.lr, betas=(0.9, 0.95))', type=str,
|
||||
help="Optimizer from torch.optim [ default: AdamW(param_groups, lr=args.lr, betas=(0.9, 0.95)) ]")
|
||||
add_arg('--amp', default=0, type=int, choices=[0,1], help='enable automatic mixed precision training')
|
||||
# validation
|
||||
add_arg('--val_dataset', type=str, default='', help="Validation sets, multiple separated by + (empty string means that no validation is performed)")
|
||||
add_arg('--tile_conf_mode', type=str, default_stereo='conf_expsigmoid_15_3', default_flow='conf_expsigmoid_10_5', help='Weights for tile aggregation')
|
||||
add_arg('--val_overlap', default=0.7, type=float, help='Overlap value for the tiling')
|
||||
# others
|
||||
add_arg('--num_workers', default=8, type=int)
|
||||
add_arg('--eval_every', type=int, default=1, help='Val loss evaluation frequency')
|
||||
add_arg('--save_every', type=int, default=1, help='Save checkpoint frequency')
|
||||
add_arg('--start_from', type=str, default=None, help='Start training using weights from an other model (eg for finetuning)')
|
||||
add_arg('--tboard_log_step', type=int, default=100, help='Log to tboard every so many steps')
|
||||
add_arg('--dist_url', default='env://', help='url used to set up distributed training')
|
||||
|
||||
return parser
|
||||
|
||||
|
||||
def main(args):
|
||||
misc.init_distributed_mode(args)
|
||||
global_rank = misc.get_rank()
|
||||
num_tasks = misc.get_world_size()
|
||||
|
||||
assert os.path.isfile(args.pretrained)
|
||||
print("output_dir: "+args.output_dir)
|
||||
os.makedirs(args.output_dir, exist_ok=True)
|
||||
|
||||
# fix the seed for reproducibility
|
||||
seed = args.seed + misc.get_rank()
|
||||
torch.manual_seed(seed)
|
||||
np.random.seed(seed)
|
||||
cudnn.benchmark = True
|
||||
|
||||
# Metrics / criterion
|
||||
device = torch.device('cuda') if torch.cuda.is_available() else torch.device('cpu')
|
||||
metrics = (StereoMetrics if args.task=='stereo' else FlowMetrics)().to(device)
|
||||
criterion = eval(args.criterion).to(device)
|
||||
print('Criterion: ', args.criterion)
|
||||
|
||||
# Prepare model
|
||||
assert os.path.isfile(args.pretrained)
|
||||
ckpt = torch.load(args.pretrained, 'cpu')
|
||||
croco_args = croco_args_from_ckpt(ckpt)
|
||||
croco_args['img_size'] = (args.crop[0], args.crop[1])
|
||||
print('Croco args: '+str(croco_args))
|
||||
args.croco_args = croco_args # saved for test time
|
||||
# prepare head
|
||||
num_channels = {'stereo': 1, 'flow': 2}[args.task]
|
||||
if criterion.with_conf: num_channels += 1
|
||||
print(f'Building head PixelwiseTaskWithDPT() with {num_channels} channel(s)')
|
||||
head = PixelwiseTaskWithDPT()
|
||||
head.num_channels = num_channels
|
||||
# build model and load pretrained weights
|
||||
model = CroCoDownstreamBinocular(head, **croco_args)
|
||||
interpolate_pos_embed(model, ckpt['model'])
|
||||
msg = model.load_state_dict(ckpt['model'], strict=False)
|
||||
print(msg)
|
||||
|
||||
total_params = sum(p.numel() for p in model.parameters())
|
||||
total_params_trainable = sum(p.numel() for p in model.parameters() if p.requires_grad)
|
||||
print(f"Total params: {total_params}")
|
||||
print(f"Total params trainable: {total_params_trainable}")
|
||||
model_without_ddp = model.to(device)
|
||||
|
||||
eff_batch_size = args.batch_size * args.accum_iter * misc.get_world_size()
|
||||
print("lr: %.2e" % args.lr)
|
||||
print("accumulate grad iterations: %d" % args.accum_iter)
|
||||
print("effective batch size: %d" % eff_batch_size)
|
||||
|
||||
if args.distributed:
|
||||
model = torch.nn.parallel.DistributedDataParallel(model, device_ids=[args.gpu], static_graph=True)
|
||||
model_without_ddp = model.module
|
||||
|
||||
# following timm: set wd as 0 for bias and norm layers
|
||||
param_groups = misc.get_parameter_groups(model_without_ddp, args.weight_decay)
|
||||
optimizer = eval(f"torch.optim.{args.optimizer}")
|
||||
print(optimizer)
|
||||
loss_scaler = NativeScaler()
|
||||
|
||||
# automatic restart
|
||||
last_ckpt_fname = os.path.join(args.output_dir, f'checkpoint-last.pth')
|
||||
args.resume = last_ckpt_fname if os.path.isfile(last_ckpt_fname) else None
|
||||
|
||||
if not args.resume and args.start_from:
|
||||
print(f"Starting from an other model's weights: {args.start_from}")
|
||||
best_so_far = None
|
||||
args.start_epoch = 0
|
||||
ckpt = torch.load(args.start_from, 'cpu')
|
||||
msg = model_without_ddp.load_state_dict(ckpt['model'], strict=False)
|
||||
print(msg)
|
||||
else:
|
||||
best_so_far = misc.load_model(args=args, model_without_ddp=model_without_ddp, optimizer=optimizer, loss_scaler=loss_scaler)
|
||||
|
||||
if best_so_far is None: best_so_far = np.inf
|
||||
|
||||
# tensorboard
|
||||
log_writer = None
|
||||
if global_rank == 0 and args.output_dir is not None:
|
||||
log_writer = SummaryWriter(log_dir=args.output_dir, purge_step=args.start_epoch*1000)
|
||||
|
||||
# dataset and loader
|
||||
print('Building Train Data loader for dataset: ', args.dataset)
|
||||
train_dataset = (get_train_dataset_stereo if args.task=='stereo' else get_train_dataset_flow)(args.dataset, crop_size=args.crop)
|
||||
def _print_repr_dataset(d):
|
||||
if isinstance(d, torch.utils.data.dataset.ConcatDataset):
|
||||
for dd in d.datasets:
|
||||
_print_repr_dataset(dd)
|
||||
else:
|
||||
print(repr(d))
|
||||
_print_repr_dataset(train_dataset)
|
||||
print(' total length:', len(train_dataset))
|
||||
if args.distributed:
|
||||
sampler_train = torch.utils.data.DistributedSampler(
|
||||
train_dataset, num_replicas=num_tasks, rank=global_rank, shuffle=True
|
||||
)
|
||||
else:
|
||||
sampler_train = torch.utils.data.RandomSampler(train_dataset)
|
||||
data_loader_train = torch.utils.data.DataLoader(
|
||||
train_dataset, sampler=sampler_train,
|
||||
batch_size=args.batch_size,
|
||||
num_workers=args.num_workers,
|
||||
pin_memory=True,
|
||||
drop_last=True,
|
||||
)
|
||||
if args.val_dataset=='':
|
||||
data_loaders_val = None
|
||||
else:
|
||||
print('Building Val Data loader for datasets: ', args.val_dataset)
|
||||
val_datasets = (get_test_datasets_stereo if args.task=='stereo' else get_test_datasets_flow)(args.val_dataset)
|
||||
for val_dataset in val_datasets: print(repr(val_dataset))
|
||||
data_loaders_val = [DataLoader(val_dataset, batch_size=1, shuffle=False, num_workers=args.num_workers, pin_memory=True, drop_last=False) for val_dataset in val_datasets]
|
||||
bestmetric = ("AVG_" if len(data_loaders_val)>1 else str(data_loaders_val[0].dataset)+'_')+args.bestmetric
|
||||
|
||||
print(f"Start training for {args.epochs} epochs")
|
||||
start_time = time.time()
|
||||
# Training Loop
|
||||
for epoch in range(args.start_epoch, args.epochs):
|
||||
|
||||
if args.distributed: data_loader_train.sampler.set_epoch(epoch)
|
||||
|
||||
# Train
|
||||
epoch_start = time.time()
|
||||
train_stats = train_one_epoch(model, criterion, metrics, data_loader_train, optimizer, device, epoch, loss_scaler, log_writer=log_writer, args=args)
|
||||
epoch_time = time.time() - epoch_start
|
||||
|
||||
if args.distributed: dist.barrier()
|
||||
|
||||
# Validation (current naive implementation runs the validation on every gpu ... not smart ...)
|
||||
if data_loaders_val is not None and args.eval_every > 0 and (epoch+1) % args.eval_every == 0:
|
||||
val_epoch_start = time.time()
|
||||
val_stats = validate_one_epoch(model, criterion, metrics, data_loaders_val, device, epoch, log_writer=log_writer, args=args)
|
||||
val_epoch_time = time.time() - val_epoch_start
|
||||
|
||||
val_best = val_stats[bestmetric]
|
||||
|
||||
# Save best of all
|
||||
if val_best <= best_so_far:
|
||||
best_so_far = val_best
|
||||
misc.save_model(args=args, model_without_ddp=model_without_ddp, optimizer=optimizer, loss_scaler=loss_scaler, epoch=epoch, best_so_far=best_so_far, fname='best')
|
||||
|
||||
log_stats = {**{f'train_{k}': v for k, v in train_stats.items()},
|
||||
'epoch': epoch,
|
||||
**{f'val_{k}': v for k, v in val_stats.items()}}
|
||||
else:
|
||||
log_stats = {**{f'train_{k}': v for k, v in train_stats.items()},
|
||||
'epoch': epoch,}
|
||||
|
||||
if args.distributed: dist.barrier()
|
||||
|
||||
# Save stuff
|
||||
if args.output_dir and ((epoch+1) % args.save_every == 0 or epoch + 1 == args.epochs):
|
||||
misc.save_model(args=args, model_without_ddp=model_without_ddp, optimizer=optimizer, loss_scaler=loss_scaler, epoch=epoch, best_so_far=best_so_far, fname='last')
|
||||
|
||||
if args.output_dir:
|
||||
if log_writer is not None:
|
||||
log_writer.flush()
|
||||
with open(os.path.join(args.output_dir, "log.txt"), mode="a", encoding="utf-8") as f:
|
||||
f.write(json.dumps(log_stats) + "\n")
|
||||
|
||||
total_time = time.time() - start_time
|
||||
total_time_str = str(datetime.timedelta(seconds=int(total_time)))
|
||||
print('Training time {}'.format(total_time_str))
|
||||
|
||||
if __name__ == '__main__':
|
||||
args = get_args_parser()
|
||||
args = args.parse_args()
|
||||
main(args)
|
||||
+463
@@ -0,0 +1,463 @@
|
||||
# Copyright (C) 2022-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# utilitary functions for CroCo
|
||||
# --------------------------------------------------------
|
||||
# References:
|
||||
# MAE: https://github.com/facebookresearch/mae
|
||||
# DeiT: https://github.com/facebookresearch/deit
|
||||
# BEiT: https://github.com/microsoft/unilm/tree/master/beit
|
||||
# --------------------------------------------------------
|
||||
|
||||
import builtins
|
||||
import datetime
|
||||
import os
|
||||
import time
|
||||
import math
|
||||
import json
|
||||
from collections import defaultdict, deque
|
||||
from pathlib import Path
|
||||
import numpy as np
|
||||
|
||||
import torch
|
||||
import torch.distributed as dist
|
||||
from torch import inf
|
||||
|
||||
class SmoothedValue(object):
|
||||
"""Track a series of values and provide access to smoothed values over a
|
||||
window or the global series average.
|
||||
"""
|
||||
|
||||
def __init__(self, window_size=20, fmt=None):
|
||||
if fmt is None:
|
||||
fmt = "{median:.4f} ({global_avg:.4f})"
|
||||
self.deque = deque(maxlen=window_size)
|
||||
self.total = 0.0
|
||||
self.count = 0
|
||||
self.fmt = fmt
|
||||
|
||||
def update(self, value, n=1):
|
||||
self.deque.append(value)
|
||||
self.count += n
|
||||
self.total += value * n
|
||||
|
||||
def synchronize_between_processes(self):
|
||||
"""
|
||||
Warning: does not synchronize the deque!
|
||||
"""
|
||||
if not is_dist_avail_and_initialized():
|
||||
return
|
||||
t = torch.tensor([self.count, self.total], dtype=torch.float64, device='cuda')
|
||||
dist.barrier()
|
||||
dist.all_reduce(t)
|
||||
t = t.tolist()
|
||||
self.count = int(t[0])
|
||||
self.total = t[1]
|
||||
|
||||
@property
|
||||
def median(self):
|
||||
d = torch.tensor(list(self.deque))
|
||||
return d.median().item()
|
||||
|
||||
@property
|
||||
def avg(self):
|
||||
d = torch.tensor(list(self.deque), dtype=torch.float32)
|
||||
return d.mean().item()
|
||||
|
||||
@property
|
||||
def global_avg(self):
|
||||
return self.total / self.count
|
||||
|
||||
@property
|
||||
def max(self):
|
||||
return max(self.deque)
|
||||
|
||||
@property
|
||||
def value(self):
|
||||
return self.deque[-1]
|
||||
|
||||
def __str__(self):
|
||||
return self.fmt.format(
|
||||
median=self.median,
|
||||
avg=self.avg,
|
||||
global_avg=self.global_avg,
|
||||
max=self.max,
|
||||
value=self.value)
|
||||
|
||||
|
||||
class MetricLogger(object):
|
||||
def __init__(self, delimiter="\t"):
|
||||
self.meters = defaultdict(SmoothedValue)
|
||||
self.delimiter = delimiter
|
||||
|
||||
def update(self, **kwargs):
|
||||
for k, v in kwargs.items():
|
||||
if v is None:
|
||||
continue
|
||||
if isinstance(v, torch.Tensor):
|
||||
v = v.item()
|
||||
assert isinstance(v, (float, int))
|
||||
self.meters[k].update(v)
|
||||
|
||||
def __getattr__(self, attr):
|
||||
if attr in self.meters:
|
||||
return self.meters[attr]
|
||||
if attr in self.__dict__:
|
||||
return self.__dict__[attr]
|
||||
raise AttributeError("'{}' object has no attribute '{}'".format(
|
||||
type(self).__name__, attr))
|
||||
|
||||
def __str__(self):
|
||||
loss_str = []
|
||||
for name, meter in self.meters.items():
|
||||
loss_str.append(
|
||||
"{}: {}".format(name, str(meter))
|
||||
)
|
||||
return self.delimiter.join(loss_str)
|
||||
|
||||
def synchronize_between_processes(self):
|
||||
for meter in self.meters.values():
|
||||
meter.synchronize_between_processes()
|
||||
|
||||
def add_meter(self, name, meter):
|
||||
self.meters[name] = meter
|
||||
|
||||
def log_every(self, iterable, print_freq, header=None, max_iter=None):
|
||||
i = 0
|
||||
if not header:
|
||||
header = ''
|
||||
start_time = time.time()
|
||||
end = time.time()
|
||||
iter_time = SmoothedValue(fmt='{avg:.4f}')
|
||||
data_time = SmoothedValue(fmt='{avg:.4f}')
|
||||
len_iterable = min(len(iterable), max_iter) if max_iter else len(iterable)
|
||||
space_fmt = ':' + str(len(str(len_iterable))) + 'd'
|
||||
log_msg = [
|
||||
header,
|
||||
'[{0' + space_fmt + '}/{1}]',
|
||||
'eta: {eta}',
|
||||
'{meters}',
|
||||
'time: {time}',
|
||||
'data: {data}'
|
||||
]
|
||||
if torch.cuda.is_available():
|
||||
log_msg.append('max mem: {memory:.0f}')
|
||||
log_msg = self.delimiter.join(log_msg)
|
||||
MB = 1024.0 * 1024.0
|
||||
for it,obj in enumerate(iterable):
|
||||
data_time.update(time.time() - end)
|
||||
yield obj
|
||||
iter_time.update(time.time() - end)
|
||||
if i % print_freq == 0 or i == len_iterable - 1:
|
||||
eta_seconds = iter_time.global_avg * (len_iterable - i)
|
||||
eta_string = str(datetime.timedelta(seconds=int(eta_seconds)))
|
||||
if torch.cuda.is_available():
|
||||
print(log_msg.format(
|
||||
i, len_iterable, eta=eta_string,
|
||||
meters=str(self),
|
||||
time=str(iter_time), data=str(data_time),
|
||||
memory=torch.cuda.max_memory_allocated() / MB))
|
||||
else:
|
||||
print(log_msg.format(
|
||||
i, len_iterable, eta=eta_string,
|
||||
meters=str(self),
|
||||
time=str(iter_time), data=str(data_time)))
|
||||
i += 1
|
||||
end = time.time()
|
||||
if max_iter and it >= max_iter:
|
||||
break
|
||||
total_time = time.time() - start_time
|
||||
total_time_str = str(datetime.timedelta(seconds=int(total_time)))
|
||||
print('{} Total time: {} ({:.4f} s / it)'.format(
|
||||
header, total_time_str, total_time / len_iterable))
|
||||
|
||||
|
||||
def setup_for_distributed(is_master):
|
||||
"""
|
||||
This function disables printing when not in master process
|
||||
"""
|
||||
builtin_print = builtins.print
|
||||
|
||||
def print(*args, **kwargs):
|
||||
force = kwargs.pop('force', False)
|
||||
force = force or (get_world_size() > 8)
|
||||
if is_master or force:
|
||||
now = datetime.datetime.now().time()
|
||||
builtin_print('[{}] '.format(now), end='') # print with time stamp
|
||||
builtin_print(*args, **kwargs)
|
||||
|
||||
builtins.print = print
|
||||
|
||||
|
||||
def is_dist_avail_and_initialized():
|
||||
if not dist.is_available():
|
||||
return False
|
||||
if not dist.is_initialized():
|
||||
return False
|
||||
return True
|
||||
|
||||
|
||||
def get_world_size():
|
||||
if not is_dist_avail_and_initialized():
|
||||
return 1
|
||||
return dist.get_world_size()
|
||||
|
||||
|
||||
def get_rank():
|
||||
if not is_dist_avail_and_initialized():
|
||||
return 0
|
||||
return dist.get_rank()
|
||||
|
||||
|
||||
def is_main_process():
|
||||
return get_rank() == 0
|
||||
|
||||
|
||||
def save_on_master(*args, **kwargs):
|
||||
if is_main_process():
|
||||
torch.save(*args, **kwargs)
|
||||
|
||||
|
||||
def init_distributed_mode(args):
|
||||
nodist = args.nodist if hasattr(args,'nodist') else False
|
||||
if 'RANK' in os.environ and 'WORLD_SIZE' in os.environ and not nodist:
|
||||
args.rank = int(os.environ["RANK"])
|
||||
args.world_size = int(os.environ['WORLD_SIZE'])
|
||||
args.gpu = int(os.environ['LOCAL_RANK'])
|
||||
else:
|
||||
print('Not using distributed mode')
|
||||
setup_for_distributed(is_master=True) # hack
|
||||
args.distributed = False
|
||||
return
|
||||
|
||||
args.distributed = True
|
||||
|
||||
torch.cuda.set_device(args.gpu)
|
||||
args.dist_backend = 'nccl'
|
||||
print('| distributed init (rank {}): {}, gpu {}'.format(
|
||||
args.rank, args.dist_url, args.gpu), flush=True)
|
||||
torch.distributed.init_process_group(backend=args.dist_backend, init_method=args.dist_url,
|
||||
world_size=args.world_size, rank=args.rank)
|
||||
torch.distributed.barrier()
|
||||
setup_for_distributed(args.rank == 0)
|
||||
|
||||
|
||||
class NativeScalerWithGradNormCount:
|
||||
state_dict_key = "amp_scaler"
|
||||
|
||||
def __init__(self, enabled=True):
|
||||
self._scaler = torch.cuda.amp.GradScaler(enabled=enabled)
|
||||
|
||||
def __call__(self, loss, optimizer, clip_grad=None, parameters=None, create_graph=False, update_grad=True):
|
||||
self._scaler.scale(loss).backward(create_graph=create_graph)
|
||||
if update_grad:
|
||||
if clip_grad is not None:
|
||||
assert parameters is not None
|
||||
self._scaler.unscale_(optimizer) # unscale the gradients of optimizer's assigned params in-place
|
||||
norm = torch.nn.utils.clip_grad_norm_(parameters, clip_grad)
|
||||
else:
|
||||
self._scaler.unscale_(optimizer)
|
||||
norm = get_grad_norm_(parameters)
|
||||
self._scaler.step(optimizer)
|
||||
self._scaler.update()
|
||||
else:
|
||||
norm = None
|
||||
return norm
|
||||
|
||||
def state_dict(self):
|
||||
return self._scaler.state_dict()
|
||||
|
||||
def load_state_dict(self, state_dict):
|
||||
self._scaler.load_state_dict(state_dict)
|
||||
|
||||
|
||||
def get_grad_norm_(parameters, norm_type: float = 2.0) -> torch.Tensor:
|
||||
if isinstance(parameters, torch.Tensor):
|
||||
parameters = [parameters]
|
||||
parameters = [p for p in parameters if p.grad is not None]
|
||||
norm_type = float(norm_type)
|
||||
if len(parameters) == 0:
|
||||
return torch.tensor(0.)
|
||||
device = parameters[0].grad.device
|
||||
if norm_type == inf:
|
||||
total_norm = max(p.grad.detach().abs().max().to(device) for p in parameters)
|
||||
else:
|
||||
total_norm = torch.norm(torch.stack([torch.norm(p.grad.detach(), norm_type).to(device) for p in parameters]), norm_type)
|
||||
return total_norm
|
||||
|
||||
|
||||
|
||||
|
||||
def save_model(args, epoch, model_without_ddp, optimizer, loss_scaler, fname=None, best_so_far=None):
|
||||
output_dir = Path(args.output_dir)
|
||||
if fname is None: fname = str(epoch)
|
||||
checkpoint_path = output_dir / ('checkpoint-%s.pth' % fname)
|
||||
to_save = {
|
||||
'model': model_without_ddp.state_dict(),
|
||||
'optimizer': optimizer.state_dict(),
|
||||
'scaler': loss_scaler.state_dict(),
|
||||
'args': args,
|
||||
'epoch': epoch,
|
||||
}
|
||||
if best_so_far is not None: to_save['best_so_far'] = best_so_far
|
||||
print(f'>> Saving model to {checkpoint_path} ...')
|
||||
save_on_master(to_save, checkpoint_path)
|
||||
|
||||
|
||||
def load_model(args, model_without_ddp, optimizer, loss_scaler):
|
||||
args.start_epoch = 0
|
||||
best_so_far = None
|
||||
if args.resume is not None:
|
||||
if args.resume.startswith('https'):
|
||||
checkpoint = torch.hub.load_state_dict_from_url(
|
||||
args.resume, map_location='cpu', check_hash=True)
|
||||
else:
|
||||
checkpoint = torch.load(args.resume, map_location='cpu')
|
||||
print("Resume checkpoint %s" % args.resume)
|
||||
model_without_ddp.load_state_dict(checkpoint['model'], strict=False)
|
||||
args.start_epoch = checkpoint['epoch'] + 1
|
||||
optimizer.load_state_dict(checkpoint['optimizer'])
|
||||
if 'scaler' in checkpoint:
|
||||
loss_scaler.load_state_dict(checkpoint['scaler'])
|
||||
if 'best_so_far' in checkpoint:
|
||||
best_so_far = checkpoint['best_so_far']
|
||||
print(" & best_so_far={:g}".format(best_so_far))
|
||||
else:
|
||||
print("")
|
||||
print("With optim & sched! start_epoch={:d}".format(args.start_epoch), end='')
|
||||
return best_so_far
|
||||
|
||||
def all_reduce_mean(x):
|
||||
world_size = get_world_size()
|
||||
if world_size > 1:
|
||||
x_reduce = torch.tensor(x).cuda()
|
||||
dist.all_reduce(x_reduce)
|
||||
x_reduce /= world_size
|
||||
return x_reduce.item()
|
||||
else:
|
||||
return x
|
||||
|
||||
def _replace(text, src, tgt, rm=''):
|
||||
""" Advanced string replacement.
|
||||
Given a text:
|
||||
- replace all elements in src by the corresponding element in tgt
|
||||
- remove all elements in rm
|
||||
"""
|
||||
if len(tgt) == 1:
|
||||
tgt = tgt * len(src)
|
||||
assert len(src) == len(tgt), f"'{src}' and '{tgt}' should have the same len"
|
||||
for s,t in zip(src, tgt):
|
||||
text = text.replace(s,t)
|
||||
for c in rm:
|
||||
text = text.replace(c,'')
|
||||
return text
|
||||
|
||||
def filename( obj ):
|
||||
""" transform a python obj or cmd into a proper filename.
|
||||
- \1 gets replaced by slash '/'
|
||||
- \2 gets replaced by comma ','
|
||||
"""
|
||||
if not isinstance(obj, str):
|
||||
obj = repr(obj)
|
||||
obj = str(obj).replace('()','')
|
||||
obj = _replace(obj, '_,(*/\1\2','-__x%/,', rm=' )\'"')
|
||||
assert all(len(s) < 256 for s in obj.split(os.sep)), 'filename too long (>256 characters):\n'+obj
|
||||
return obj
|
||||
|
||||
def _get_num_layer_for_vit(var_name, enc_depth, dec_depth):
|
||||
if var_name in ("cls_token", "mask_token", "pos_embed", "global_tokens"):
|
||||
return 0
|
||||
elif var_name.startswith("patch_embed"):
|
||||
return 0
|
||||
elif var_name.startswith("enc_blocks"):
|
||||
layer_id = int(var_name.split('.')[1])
|
||||
return layer_id + 1
|
||||
elif var_name.startswith('decoder_embed') or var_name.startswith('enc_norm'): # part of the last black
|
||||
return enc_depth
|
||||
elif var_name.startswith('dec_blocks'):
|
||||
layer_id = int(var_name.split('.')[1])
|
||||
return enc_depth + layer_id + 1
|
||||
elif var_name.startswith('dec_norm'): # part of the last block
|
||||
return enc_depth + dec_depth
|
||||
elif any(var_name.startswith(k) for k in ['head','prediction_head']):
|
||||
return enc_depth + dec_depth + 1
|
||||
else:
|
||||
raise NotImplementedError(var_name)
|
||||
|
||||
def get_parameter_groups(model, weight_decay, layer_decay=1.0, skip_list=(), no_lr_scale_list=[]):
|
||||
parameter_group_names = {}
|
||||
parameter_group_vars = {}
|
||||
enc_depth, dec_depth = None, None
|
||||
# prepare layer decay values
|
||||
assert layer_decay==1.0 or 0.<layer_decay<1.
|
||||
if layer_decay<1.:
|
||||
enc_depth = model.enc_depth
|
||||
dec_depth = model.dec_depth if hasattr(model, 'dec_blocks') else 0
|
||||
num_layers = enc_depth+dec_depth
|
||||
layer_decay_values = list(layer_decay ** (num_layers + 1 - i) for i in range(num_layers + 2))
|
||||
|
||||
for name, param in model.named_parameters():
|
||||
if not param.requires_grad:
|
||||
continue # frozen weights
|
||||
|
||||
# Assign weight decay values
|
||||
if len(param.shape) == 1 or name.endswith(".bias") or name in skip_list:
|
||||
group_name = "no_decay"
|
||||
this_weight_decay = 0.
|
||||
else:
|
||||
group_name = "decay"
|
||||
this_weight_decay = weight_decay
|
||||
|
||||
# Assign layer ID for LR scaling
|
||||
if layer_decay<1.:
|
||||
skip_scale = False
|
||||
layer_id = _get_num_layer_for_vit(name, enc_depth, dec_depth)
|
||||
group_name = "layer_%d_%s" % (layer_id, group_name)
|
||||
if name in no_lr_scale_list:
|
||||
skip_scale = True
|
||||
group_name = f'{group_name}_no_lr_scale'
|
||||
else:
|
||||
layer_id = 0
|
||||
skip_scale = True
|
||||
|
||||
if group_name not in parameter_group_names:
|
||||
if not skip_scale:
|
||||
scale = layer_decay_values[layer_id]
|
||||
else:
|
||||
scale = 1.
|
||||
|
||||
parameter_group_names[group_name] = {
|
||||
"weight_decay": this_weight_decay,
|
||||
"params": [],
|
||||
"lr_scale": scale
|
||||
}
|
||||
parameter_group_vars[group_name] = {
|
||||
"weight_decay": this_weight_decay,
|
||||
"params": [],
|
||||
"lr_scale": scale
|
||||
}
|
||||
|
||||
parameter_group_vars[group_name]["params"].append(param)
|
||||
parameter_group_names[group_name]["params"].append(name)
|
||||
print("Param groups = %s" % json.dumps(parameter_group_names, indent=2))
|
||||
return list(parameter_group_vars.values())
|
||||
|
||||
|
||||
|
||||
def adjust_learning_rate(optimizer, epoch, args):
|
||||
"""Decay the learning rate with half-cycle cosine after warmup"""
|
||||
|
||||
if epoch < args.warmup_epochs:
|
||||
lr = args.lr * epoch / args.warmup_epochs
|
||||
else:
|
||||
lr = args.min_lr + (args.lr - args.min_lr) * 0.5 * \
|
||||
(1. + math.cos(math.pi * (epoch - args.warmup_epochs) / (args.epochs - args.warmup_epochs)))
|
||||
|
||||
for param_group in optimizer.param_groups:
|
||||
if "lr_scale" in param_group:
|
||||
param_group["lr"] = lr * param_group["lr_scale"]
|
||||
else:
|
||||
param_group["lr"] = lr
|
||||
|
||||
return lr
|
||||
@@ -0,0 +1,13 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# DUSt3R repo root import
|
||||
# --------------------------------------------------------
|
||||
|
||||
import sys
|
||||
import os.path as path
|
||||
HERE_PATH = path.normpath(path.dirname(__file__))
|
||||
DUST3R_REPO_PATH = path.normpath(path.join(HERE_PATH, '../'))
|
||||
# workaround for sibling import
|
||||
sys.path.insert(0, DUST3R_REPO_PATH)
|
||||
@@ -0,0 +1,295 @@
|
||||
#!/usr/bin/env python3
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# Script to pre-process the CO3D dataset.
|
||||
# Usage:
|
||||
# python3 datasets_preprocess/preprocess_co3d.py --co3d_dir /path/to/co3d
|
||||
# --------------------------------------------------------
|
||||
|
||||
import argparse
|
||||
import random
|
||||
import gzip
|
||||
import json
|
||||
import os
|
||||
import os.path as osp
|
||||
|
||||
import torch
|
||||
import PIL.Image
|
||||
import numpy as np
|
||||
import cv2
|
||||
|
||||
from tqdm.auto import tqdm
|
||||
import matplotlib.pyplot as plt
|
||||
|
||||
import path_to_root # noqa
|
||||
import dust3r.datasets.utils.cropping as cropping # noqa
|
||||
|
||||
|
||||
CATEGORIES = [
|
||||
"apple", "backpack", "ball", "banana", "baseballbat", "baseballglove",
|
||||
"bench", "bicycle", "book", "bottle", "bowl", "broccoli", "cake", "car", "carrot",
|
||||
"cellphone", "chair", "couch", "cup", "donut", "frisbee", "hairdryer", "handbag",
|
||||
"hotdog", "hydrant", "keyboard", "kite", "laptop", "microwave",
|
||||
"motorcycle",
|
||||
"mouse", "orange", "parkingmeter", "pizza", "plant", "remote", "sandwich",
|
||||
"skateboard", "stopsign",
|
||||
"suitcase", "teddybear", "toaster", "toilet", "toybus",
|
||||
"toyplane", "toytrain", "toytruck", "tv",
|
||||
"umbrella", "vase", "wineglass",
|
||||
]
|
||||
CATEGORIES_IDX = {cat: i for i, cat in enumerate(CATEGORIES)} # for seeding
|
||||
|
||||
SINGLE_SEQUENCE_CATEGORIES = sorted(set(CATEGORIES) - set(["microwave", "stopsign", "tv"]))
|
||||
|
||||
|
||||
def get_parser():
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--category", type=str, default=None)
|
||||
parser.add_argument('--single_sequence_subset', default=False, action='store_true',
|
||||
help="prepare the single_sequence_subset instead.")
|
||||
parser.add_argument("--output_dir", type=str, default="data/co3d_processed")
|
||||
parser.add_argument("--co3d_dir", type=str, required=True)
|
||||
parser.add_argument("--num_sequences_per_object", type=int, default=50)
|
||||
parser.add_argument("--seed", type=int, default=42)
|
||||
parser.add_argument("--min_quality", type=float, default=0.5, help="Minimum viewpoint quality score.")
|
||||
|
||||
parser.add_argument("--img_size", type=int, default=512,
|
||||
help=("lower dimension will be >= img_size * 3/4, and max dimension will be >= img_size"))
|
||||
return parser
|
||||
|
||||
|
||||
def convert_ndc_to_pinhole(focal_length, principal_point, image_size):
|
||||
focal_length = np.array(focal_length)
|
||||
principal_point = np.array(principal_point)
|
||||
image_size_wh = np.array([image_size[1], image_size[0]])
|
||||
half_image_size = image_size_wh / 2
|
||||
rescale = half_image_size.min()
|
||||
principal_point_px = half_image_size - principal_point * rescale
|
||||
focal_length_px = focal_length * rescale
|
||||
fx, fy = focal_length_px[0], focal_length_px[1]
|
||||
cx, cy = principal_point_px[0], principal_point_px[1]
|
||||
K = np.array([[fx, 0.0, cx], [0.0, fy, cy], [0.0, 0.0, 1.0]], dtype=np.float32)
|
||||
return K
|
||||
|
||||
|
||||
def opencv_from_cameras_projection(R, T, focal, p0, image_size):
|
||||
R = torch.from_numpy(R)[None, :, :]
|
||||
T = torch.from_numpy(T)[None, :]
|
||||
focal = torch.from_numpy(focal)[None, :]
|
||||
p0 = torch.from_numpy(p0)[None, :]
|
||||
image_size = torch.from_numpy(image_size)[None, :]
|
||||
|
||||
R_pytorch3d = R.clone()
|
||||
T_pytorch3d = T.clone()
|
||||
focal_pytorch3d = focal
|
||||
p0_pytorch3d = p0
|
||||
T_pytorch3d[:, :2] *= -1
|
||||
R_pytorch3d[:, :, :2] *= -1
|
||||
tvec = T_pytorch3d
|
||||
R = R_pytorch3d.permute(0, 2, 1)
|
||||
|
||||
# Retype the image_size correctly and flip to width, height.
|
||||
image_size_wh = image_size.to(R).flip(dims=(1,))
|
||||
|
||||
# NDC to screen conversion.
|
||||
scale = image_size_wh.to(R).min(dim=1, keepdim=True)[0] / 2.0
|
||||
scale = scale.expand(-1, 2)
|
||||
c0 = image_size_wh / 2.0
|
||||
|
||||
principal_point = -p0_pytorch3d * scale + c0
|
||||
focal_length = focal_pytorch3d * scale
|
||||
|
||||
camera_matrix = torch.zeros_like(R)
|
||||
camera_matrix[:, :2, 2] = principal_point
|
||||
camera_matrix[:, 2, 2] = 1.0
|
||||
camera_matrix[:, 0, 0] = focal_length[:, 0]
|
||||
camera_matrix[:, 1, 1] = focal_length[:, 1]
|
||||
return R[0], tvec[0], camera_matrix[0]
|
||||
|
||||
|
||||
def get_set_list(category_dir, split, is_single_sequence_subset=False):
|
||||
listfiles = os.listdir(osp.join(category_dir, "set_lists"))
|
||||
if is_single_sequence_subset:
|
||||
# not all objects have manyview_dev
|
||||
subset_list_files = [f for f in listfiles if "manyview_dev" in f]
|
||||
else:
|
||||
subset_list_files = [f for f in listfiles if f"fewview_train" in f]
|
||||
|
||||
sequences_all = []
|
||||
for subset_list_file in subset_list_files:
|
||||
with open(osp.join(category_dir, "set_lists", subset_list_file)) as f:
|
||||
subset_lists_data = json.load(f)
|
||||
sequences_all.extend(subset_lists_data[split])
|
||||
|
||||
return sequences_all
|
||||
|
||||
|
||||
def prepare_sequences(category, co3d_dir, output_dir, img_size, split, min_quality, max_num_sequences_per_object,
|
||||
seed, is_single_sequence_subset=False):
|
||||
random.seed(seed)
|
||||
category_dir = osp.join(co3d_dir, category)
|
||||
category_output_dir = osp.join(output_dir, category)
|
||||
sequences_all = get_set_list(category_dir, split, is_single_sequence_subset)
|
||||
sequences_numbers = sorted(set(seq_name for seq_name, _, _ in sequences_all))
|
||||
|
||||
frame_file = osp.join(category_dir, "frame_annotations.jgz")
|
||||
sequence_file = osp.join(category_dir, "sequence_annotations.jgz")
|
||||
|
||||
with gzip.open(frame_file, "r") as fin:
|
||||
frame_data = json.loads(fin.read())
|
||||
with gzip.open(sequence_file, "r") as fin:
|
||||
sequence_data = json.loads(fin.read())
|
||||
|
||||
frame_data_processed = {}
|
||||
for f_data in frame_data:
|
||||
sequence_name = f_data["sequence_name"]
|
||||
frame_data_processed.setdefault(sequence_name, {})[f_data["frame_number"]] = f_data
|
||||
|
||||
good_quality_sequences = set()
|
||||
for seq_data in sequence_data:
|
||||
if seq_data["viewpoint_quality_score"] > min_quality:
|
||||
good_quality_sequences.add(seq_data["sequence_name"])
|
||||
|
||||
sequences_numbers = [seq_name for seq_name in sequences_numbers if seq_name in good_quality_sequences]
|
||||
if len(sequences_numbers) < max_num_sequences_per_object:
|
||||
selected_sequences_numbers = sequences_numbers
|
||||
else:
|
||||
selected_sequences_numbers = random.sample(sequences_numbers, max_num_sequences_per_object)
|
||||
|
||||
selected_sequences_numbers_dict = {seq_name: [] for seq_name in selected_sequences_numbers}
|
||||
sequences_all = [(seq_name, frame_number, filepath)
|
||||
for seq_name, frame_number, filepath in sequences_all
|
||||
if seq_name in selected_sequences_numbers_dict]
|
||||
|
||||
for seq_name, frame_number, filepath in tqdm(sequences_all):
|
||||
frame_idx = int(filepath.split('/')[-1][5:-4])
|
||||
selected_sequences_numbers_dict[seq_name].append(frame_idx)
|
||||
mask_path = filepath.replace("images", "masks").replace(".jpg", ".png")
|
||||
frame_data = frame_data_processed[seq_name][frame_number]
|
||||
focal_length = frame_data["viewpoint"]["focal_length"]
|
||||
principal_point = frame_data["viewpoint"]["principal_point"]
|
||||
image_size = frame_data["image"]["size"]
|
||||
K = convert_ndc_to_pinhole(focal_length, principal_point, image_size)
|
||||
R, tvec, camera_intrinsics = opencv_from_cameras_projection(np.array(frame_data["viewpoint"]["R"]),
|
||||
np.array(frame_data["viewpoint"]["T"]),
|
||||
np.array(focal_length),
|
||||
np.array(principal_point),
|
||||
np.array(image_size))
|
||||
|
||||
frame_data = frame_data_processed[seq_name][frame_number]
|
||||
depth_path = os.path.join(co3d_dir, frame_data["depth"]["path"])
|
||||
assert frame_data["depth"]["scale_adjustment"] == 1.0
|
||||
image_path = os.path.join(co3d_dir, filepath)
|
||||
mask_path_full = os.path.join(co3d_dir, mask_path)
|
||||
|
||||
input_rgb_image = PIL.Image.open(image_path).convert('RGB')
|
||||
input_mask = plt.imread(mask_path_full)
|
||||
|
||||
with PIL.Image.open(depth_path) as depth_pil:
|
||||
# the image is stored with 16-bit depth but PIL reads it as I (32 bit).
|
||||
# we cast it to uint16, then reinterpret as float16, then cast to float32
|
||||
input_depthmap = (
|
||||
np.frombuffer(np.array(depth_pil, dtype=np.uint16), dtype=np.float16)
|
||||
.astype(np.float32)
|
||||
.reshape((depth_pil.size[1], depth_pil.size[0])))
|
||||
depth_mask = np.stack((input_depthmap, input_mask), axis=-1)
|
||||
H, W = input_depthmap.shape
|
||||
|
||||
camera_intrinsics = camera_intrinsics.numpy()
|
||||
cx, cy = camera_intrinsics[:2, 2].round().astype(int)
|
||||
min_margin_x = min(cx, W-cx)
|
||||
min_margin_y = min(cy, H-cy)
|
||||
|
||||
# the new window will be a rectangle of size (2*min_margin_x, 2*min_margin_y) centered on (cx,cy)
|
||||
l, t = cx - min_margin_x, cy - min_margin_y
|
||||
r, b = cx + min_margin_x, cy + min_margin_y
|
||||
crop_bbox = (l, t, r, b)
|
||||
input_rgb_image, depth_mask, input_camera_intrinsics = cropping.crop_image_depthmap(
|
||||
input_rgb_image, depth_mask, camera_intrinsics, crop_bbox)
|
||||
|
||||
# try to set the lower dimension to img_size * 3/4 -> img_size=512 => 384
|
||||
scale_final = ((img_size * 3 // 4) / min(H, W)) + 1e-8
|
||||
output_resolution = np.floor(np.array([W, H]) * scale_final).astype(int)
|
||||
if max(output_resolution) < img_size:
|
||||
# let's put the max dimension to img_size
|
||||
scale_final = (img_size / max(H, W)) + 1e-8
|
||||
output_resolution = np.floor(np.array([W, H]) * scale_final).astype(int)
|
||||
|
||||
input_rgb_image, depth_mask, input_camera_intrinsics = cropping.rescale_image_depthmap(
|
||||
input_rgb_image, depth_mask, input_camera_intrinsics, output_resolution)
|
||||
input_depthmap = depth_mask[:, :, 0]
|
||||
input_mask = depth_mask[:, :, 1]
|
||||
|
||||
# generate and adjust camera pose
|
||||
camera_pose = np.eye(4, dtype=np.float32)
|
||||
camera_pose[:3, :3] = R
|
||||
camera_pose[:3, 3] = tvec
|
||||
camera_pose = np.linalg.inv(camera_pose)
|
||||
|
||||
# save crop images and depth, metadata
|
||||
save_img_path = os.path.join(output_dir, filepath)
|
||||
save_depth_path = os.path.join(output_dir, frame_data["depth"]["path"])
|
||||
save_mask_path = os.path.join(output_dir, mask_path)
|
||||
os.makedirs(os.path.split(save_img_path)[0], exist_ok=True)
|
||||
os.makedirs(os.path.split(save_depth_path)[0], exist_ok=True)
|
||||
os.makedirs(os.path.split(save_mask_path)[0], exist_ok=True)
|
||||
|
||||
input_rgb_image.save(save_img_path)
|
||||
scaled_depth_map = (input_depthmap / np.max(input_depthmap) * 65535).astype(np.uint16)
|
||||
cv2.imwrite(save_depth_path, scaled_depth_map)
|
||||
cv2.imwrite(save_mask_path, (input_mask * 255).astype(np.uint8))
|
||||
|
||||
save_meta_path = save_img_path.replace('jpg', 'npz')
|
||||
np.savez(save_meta_path, camera_intrinsics=input_camera_intrinsics,
|
||||
camera_pose=camera_pose, maximum_depth=np.max(input_depthmap))
|
||||
|
||||
return selected_sequences_numbers_dict
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = get_parser()
|
||||
args = parser.parse_args()
|
||||
assert args.co3d_dir != args.output_dir
|
||||
if args.category is None:
|
||||
if args.single_sequence_subset:
|
||||
categories = SINGLE_SEQUENCE_CATEGORIES
|
||||
else:
|
||||
categories = CATEGORIES
|
||||
else:
|
||||
categories = [args.category]
|
||||
os.makedirs(args.output_dir, exist_ok=True)
|
||||
|
||||
for split in ['train', 'test']:
|
||||
selected_sequences_path = os.path.join(args.output_dir, f'selected_seqs_{split}.json')
|
||||
if os.path.isfile(selected_sequences_path):
|
||||
continue
|
||||
|
||||
all_selected_sequences = {}
|
||||
for category in categories:
|
||||
category_output_dir = osp.join(args.output_dir, category)
|
||||
os.makedirs(category_output_dir, exist_ok=True)
|
||||
category_selected_sequences_path = os.path.join(category_output_dir, f'selected_seqs_{split}.json')
|
||||
if os.path.isfile(category_selected_sequences_path):
|
||||
with open(category_selected_sequences_path, 'r') as fid:
|
||||
category_selected_sequences = json.load(fid)
|
||||
else:
|
||||
print(f"Processing {split} - category = {category}")
|
||||
category_selected_sequences = prepare_sequences(
|
||||
category=category,
|
||||
co3d_dir=args.co3d_dir,
|
||||
output_dir=args.output_dir,
|
||||
img_size=args.img_size,
|
||||
split=split,
|
||||
min_quality=args.min_quality,
|
||||
max_num_sequences_per_object=args.num_sequences_per_object,
|
||||
seed=args.seed + CATEGORIES_IDX[category],
|
||||
is_single_sequence_subset=args.single_sequence_subset
|
||||
)
|
||||
with open(category_selected_sequences_path, 'w') as file:
|
||||
json.dump(category_selected_sequences, file)
|
||||
|
||||
all_selected_sequences[category] = category_selected_sequences
|
||||
with open(selected_sequences_path, 'w') as file:
|
||||
json.dump(all_selected_sequences, file)
|
||||
@@ -0,0 +1,2 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
@@ -0,0 +1,29 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# global alignment optimization wrapper function
|
||||
# --------------------------------------------------------
|
||||
from enum import Enum
|
||||
|
||||
from .optimizer import PointCloudOptimizer
|
||||
from .pair_viewer import PairViewer
|
||||
|
||||
|
||||
class GlobalAlignerMode(Enum):
|
||||
PointCloudOptimizer = "PointCloudOptimizer"
|
||||
PairViewer = "PairViewer"
|
||||
|
||||
|
||||
def global_aligner(dust3r_output, device, mode=GlobalAlignerMode.PointCloudOptimizer, **optim_kw):
|
||||
# extract all inputs
|
||||
view1, view2, pred1, pred2 = [dust3r_output[k] for k in 'view1 view2 pred1 pred2'.split()]
|
||||
# build the optimizer
|
||||
if mode == GlobalAlignerMode.PointCloudOptimizer:
|
||||
net = PointCloudOptimizer(view1, view2, pred1, pred2, **optim_kw).to(device)
|
||||
elif mode == GlobalAlignerMode.PairViewer:
|
||||
net = PairViewer(view1, view2, pred1, pred2, **optim_kw).to(device)
|
||||
else:
|
||||
raise NotImplementedError(f'Unknown mode {mode}')
|
||||
|
||||
return net
|
||||
@@ -0,0 +1,375 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# Base class for the global alignement procedure
|
||||
# --------------------------------------------------------
|
||||
from copy import deepcopy
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import roma
|
||||
from copy import deepcopy
|
||||
import tqdm
|
||||
|
||||
from dust3r.utils.geometry import inv, geotrf
|
||||
from dust3r.utils.device import to_numpy
|
||||
from dust3r.utils.image import rgb
|
||||
from dust3r.viz import SceneViz, segment_sky, auto_cam_size
|
||||
from dust3r.optim_factory import adjust_learning_rate_by_lr
|
||||
|
||||
from dust3r.cloud_opt.commons import (edge_str, ALL_DISTS, NoGradParamDict, get_imshapes, signed_expm1, signed_log1p,
|
||||
cosine_schedule, linear_schedule, get_conf_trf)
|
||||
import dust3r.cloud_opt.init_im_poses as init_fun
|
||||
|
||||
|
||||
class BasePCOptimizer (nn.Module):
|
||||
""" Optimize a global scene, given a list of pairwise observations.
|
||||
Graph node: images
|
||||
Graph edges: observations = (pred1, pred2)
|
||||
"""
|
||||
|
||||
def __init__(self, *args, **kwargs):
|
||||
if len(args) == 1 and len(kwargs) == 0:
|
||||
other = deepcopy(args[0])
|
||||
attrs = '''edges is_symmetrized dist n_imgs pred_i pred_j imshapes
|
||||
min_conf_thr conf_thr conf_i conf_j im_conf
|
||||
base_scale norm_pw_scale POSE_DIM pw_poses
|
||||
pw_adaptors pw_adaptors has_im_poses rand_pose imgs'''.split()
|
||||
self.__dict__.update({k: other[k] for k in attrs})
|
||||
else:
|
||||
self._init_from_views(*args, **kwargs)
|
||||
|
||||
def _init_from_views(self, view1, view2, pred1, pred2,
|
||||
dist='l1',
|
||||
conf='log',
|
||||
min_conf_thr=3,
|
||||
base_scale=0.5,
|
||||
allow_pw_adaptors=False,
|
||||
pw_break=20,
|
||||
rand_pose=torch.randn,
|
||||
iterationsCount=None):
|
||||
super().__init__()
|
||||
if not isinstance(view1['idx'], list):
|
||||
view1['idx'] = view1['idx'].tolist()
|
||||
if not isinstance(view2['idx'], list):
|
||||
view2['idx'] = view2['idx'].tolist()
|
||||
self.edges = [(int(i), int(j)) for i, j in zip(view1['idx'], view2['idx'])]
|
||||
self.is_symmetrized = set(self.edges) == {(j, i) for i, j in self.edges}
|
||||
self.dist = ALL_DISTS[dist]
|
||||
|
||||
self.n_imgs = self._check_edges()
|
||||
|
||||
# input data
|
||||
pred1_pts = pred1['pts3d']
|
||||
pred2_pts = pred2['pts3d_in_other_view']
|
||||
self.pred_i = NoGradParamDict({ij: pred1_pts[n] for n, ij in enumerate(self.str_edges)})
|
||||
self.pred_j = NoGradParamDict({ij: pred2_pts[n] for n, ij in enumerate(self.str_edges)})
|
||||
self.imshapes = get_imshapes(self.edges, pred1_pts, pred2_pts)
|
||||
|
||||
# work in log-scale with conf
|
||||
pred1_conf = pred1['conf']
|
||||
pred2_conf = pred2['conf']
|
||||
self.min_conf_thr = min_conf_thr
|
||||
self.conf_trf = get_conf_trf(conf)
|
||||
|
||||
self.conf_i = NoGradParamDict({ij: pred1_conf[n] for n, ij in enumerate(self.str_edges)})
|
||||
self.conf_j = NoGradParamDict({ij: pred2_conf[n] for n, ij in enumerate(self.str_edges)})
|
||||
self.im_conf = self._compute_img_conf(pred1_conf, pred2_conf)
|
||||
|
||||
# pairwise pose parameters
|
||||
self.base_scale = base_scale
|
||||
self.norm_pw_scale = True
|
||||
self.pw_break = pw_break
|
||||
self.POSE_DIM = 7
|
||||
self.pw_poses = nn.Parameter(rand_pose((self.n_edges, 1+self.POSE_DIM))) # pairwise poses
|
||||
self.pw_adaptors = nn.Parameter(torch.zeros((self.n_edges, 2))) # slight xy/z adaptation
|
||||
self.pw_adaptors.requires_grad_(allow_pw_adaptors)
|
||||
self.has_im_poses = False
|
||||
self.rand_pose = rand_pose
|
||||
|
||||
# possibly store images for show_pointcloud
|
||||
self.imgs = None
|
||||
if 'img' in view1 and 'img' in view2:
|
||||
imgs = [torch.zeros((3,)+hw) for hw in self.imshapes]
|
||||
for v in range(len(self.edges)):
|
||||
idx = view1['idx'][v]
|
||||
imgs[idx] = view1['img'][v]
|
||||
idx = view2['idx'][v]
|
||||
imgs[idx] = view2['img'][v]
|
||||
self.imgs = rgb(imgs)
|
||||
|
||||
@property
|
||||
def n_edges(self):
|
||||
return len(self.edges)
|
||||
|
||||
@property
|
||||
def str_edges(self):
|
||||
return [edge_str(i, j) for i, j in self.edges]
|
||||
|
||||
@property
|
||||
def imsizes(self):
|
||||
return [(w, h) for h, w in self.imshapes]
|
||||
|
||||
@property
|
||||
def device(self):
|
||||
return next(iter(self.parameters())).device
|
||||
|
||||
def state_dict(self, trainable=True):
|
||||
all_params = super().state_dict()
|
||||
return {k: v for k, v in all_params.items() if k.startswith(('_', 'pred_i.', 'pred_j.', 'conf_i.', 'conf_j.')) != trainable}
|
||||
|
||||
def load_state_dict(self, data):
|
||||
return super().load_state_dict(self.state_dict(trainable=False) | data)
|
||||
|
||||
def _check_edges(self):
|
||||
indices = sorted({i for edge in self.edges for i in edge})
|
||||
assert indices == list(range(len(indices))), 'bad pair indices: missing values '
|
||||
return len(indices)
|
||||
|
||||
@torch.no_grad()
|
||||
def _compute_img_conf(self, pred1_conf, pred2_conf):
|
||||
im_conf = nn.ParameterList([torch.zeros(hw, device=self.device) for hw in self.imshapes])
|
||||
for e, (i, j) in enumerate(self.edges):
|
||||
im_conf[i] = torch.maximum(im_conf[i], pred1_conf[e])
|
||||
im_conf[j] = torch.maximum(im_conf[j], pred2_conf[e])
|
||||
return im_conf
|
||||
|
||||
def get_adaptors(self):
|
||||
adapt = self.pw_adaptors
|
||||
adapt = torch.cat((adapt[:, 0:1], adapt), dim=-1) # (scale_xy, scale_xy, scale_z)
|
||||
if self.norm_pw_scale: # normalize so that the product == 1
|
||||
adapt = adapt - adapt.mean(dim=1, keepdim=True)
|
||||
return (adapt / self.pw_break).exp()
|
||||
|
||||
def _get_poses(self, poses):
|
||||
# normalize rotation
|
||||
Q = poses[:, :4]
|
||||
T = signed_expm1(poses[:, 4:7])
|
||||
RT = roma.RigidUnitQuat(Q, T).normalize().to_homogeneous()
|
||||
return RT
|
||||
|
||||
def _set_pose(self, poses, idx, R, T=None, scale=None, force=False):
|
||||
# all poses == cam-to-world
|
||||
pose = poses[idx]
|
||||
if not (pose.requires_grad or force):
|
||||
return pose
|
||||
|
||||
if R.shape == (4, 4):
|
||||
assert T is None
|
||||
T = R[:3, 3]
|
||||
R = R[:3, :3]
|
||||
|
||||
if R is not None:
|
||||
pose.data[0:4] = roma.rotmat_to_unitquat(R)
|
||||
if T is not None:
|
||||
pose.data[4:7] = signed_log1p(T / (scale or 1)) # translation is function of scale
|
||||
|
||||
if scale is not None:
|
||||
assert poses.shape[-1] in (8, 13)
|
||||
pose.data[-1] = np.log(float(scale))
|
||||
return pose
|
||||
|
||||
def get_pw_norm_scale_factor(self):
|
||||
if self.norm_pw_scale:
|
||||
# normalize scales so that things cannot go south
|
||||
# we want that exp(scale) ~= self.base_scale
|
||||
return (np.log(self.base_scale) - self.pw_poses[:, -1].mean()).exp()
|
||||
else:
|
||||
return 1 # don't norm scale for known poses
|
||||
|
||||
def get_pw_scale(self):
|
||||
scale = self.pw_poses[:, -1].exp() # (n_edges,)
|
||||
scale = scale * self.get_pw_norm_scale_factor()
|
||||
return scale
|
||||
|
||||
def get_pw_poses(self): # cam to world
|
||||
RT = self._get_poses(self.pw_poses)
|
||||
scaled_RT = RT.clone()
|
||||
scaled_RT[:, :3] *= self.get_pw_scale().view(-1, 1, 1) # scale the rotation AND translation
|
||||
return scaled_RT
|
||||
|
||||
def get_masks(self):
|
||||
return [(conf > self.min_conf_thr) for conf in self.im_conf]
|
||||
|
||||
def depth_to_pts3d(self,clip_thred=None):
|
||||
raise NotImplementedError()
|
||||
|
||||
def get_pts3d(self, raw=False,clip_thred=None):
|
||||
res = self.depth_to_pts3d(clip_thred)
|
||||
if not raw:
|
||||
res = [dm[:h*w].view(h, w, 3) for dm, (h, w) in zip(res, self.imshapes)]
|
||||
return res
|
||||
|
||||
def _set_focal(self, idx, focal, force=False):
|
||||
raise NotImplementedError()
|
||||
|
||||
def get_focals(self):
|
||||
raise NotImplementedError()
|
||||
|
||||
def get_known_focal_mask(self):
|
||||
raise NotImplementedError()
|
||||
|
||||
def get_principal_points(self):
|
||||
raise NotImplementedError()
|
||||
|
||||
def get_conf(self, mode=None):
|
||||
trf = self.conf_trf if mode is None else get_conf_trf(mode)
|
||||
return [trf(c) for c in self.im_conf]
|
||||
|
||||
def get_im_poses(self):
|
||||
raise NotImplementedError()
|
||||
|
||||
def _set_depthmap(self, idx, depth, force=False):
|
||||
raise NotImplementedError()
|
||||
|
||||
def get_depthmaps(self, raw=False):
|
||||
raise NotImplementedError()
|
||||
|
||||
@torch.no_grad()
|
||||
def clean_pointcloud(self, tol=0.001, max_bad_conf=0):
|
||||
""" Method:
|
||||
1) express all 3d points in each camera coordinate frame
|
||||
2) if they're in front of a depthmap --> then lower their confidence
|
||||
"""
|
||||
assert 0 <= tol < 1
|
||||
cams = inv(self.get_im_poses())
|
||||
K = self.get_intrinsics()
|
||||
depthmaps = self.get_depthmaps()
|
||||
res = deepcopy(self)
|
||||
|
||||
for i, pts3d in enumerate(self.depth_to_pts3d(clip_thred=None)):
|
||||
for j in range(self.n_imgs):
|
||||
if i == j:
|
||||
continue
|
||||
|
||||
# project 3dpts in other view
|
||||
Hi, Wi = self.imshapes[i]
|
||||
Hj, Wj = self.imshapes[j]
|
||||
proj = geotrf(cams[j], pts3d[:Hi*Wi]).reshape(Hi, Wi, 3)
|
||||
proj_depth = proj[:, :, 2]
|
||||
u, v = geotrf(K[j], proj, norm=1, ncol=2).round().long().unbind(-1)
|
||||
|
||||
# check which points are actually in the visible cone
|
||||
msk_i = (proj_depth > 0) & (0 <= u) & (u < Wj) & (0 <= v) & (v < Hj)
|
||||
msk_j = v[msk_i], u[msk_i]
|
||||
|
||||
# find bad points = those in front but less confident
|
||||
bad_points = (proj_depth[msk_i] < (1-tol) * depthmaps[j][msk_j]
|
||||
) & (res.im_conf[i][msk_i] < res.im_conf[j][msk_j])
|
||||
|
||||
bad_msk_i = msk_i.clone()
|
||||
bad_msk_i[msk_i] = bad_points
|
||||
res.im_conf[i][bad_msk_i] = res.im_conf[i][bad_msk_i].clip_(max=max_bad_conf)
|
||||
|
||||
return res
|
||||
|
||||
def forward(self, ret_details=False):
|
||||
pw_poses = self.get_pw_poses() # cam-to-world
|
||||
pw_adapt = self.get_adaptors()
|
||||
proj_pts3d = self.get_pts3d()
|
||||
# pre-compute pixel weights
|
||||
weight_i = {i_j: self.conf_trf(c) for i_j, c in self.conf_i.items()}
|
||||
weight_j = {i_j: self.conf_trf(c) for i_j, c in self.conf_j.items()}
|
||||
|
||||
loss = 0
|
||||
if ret_details:
|
||||
details = -torch.ones((self.n_imgs, self.n_imgs))
|
||||
|
||||
for e, (i, j) in enumerate(self.edges):
|
||||
i_j = edge_str(i, j)
|
||||
# distance in image i and j
|
||||
aligned_pred_i = geotrf(pw_poses[e], pw_adapt[e] * self.pred_i[i_j])
|
||||
aligned_pred_j = geotrf(pw_poses[e], pw_adapt[e] * self.pred_j[i_j])
|
||||
li = self.dist(proj_pts3d[i], aligned_pred_i, weight=weight_i[i_j]).mean()
|
||||
lj = self.dist(proj_pts3d[j], aligned_pred_j, weight=weight_j[i_j]).mean()
|
||||
loss = loss + li + lj
|
||||
|
||||
if ret_details:
|
||||
details[i, j] = li + lj
|
||||
loss /= self.n_edges # average over all pairs
|
||||
|
||||
if ret_details:
|
||||
return loss, details
|
||||
return loss
|
||||
|
||||
def compute_global_alignment(self, init=None, niter_PnP=10, **kw):
|
||||
if init is None:
|
||||
pass
|
||||
elif init == 'msp' or init == 'mst':
|
||||
init_fun.init_minimum_spanning_tree(self, niter_PnP=niter_PnP)
|
||||
elif init == 'known_poses':
|
||||
init_fun.init_from_known_poses(self, min_conf_thr=self.min_conf_thr, niter_PnP=niter_PnP)
|
||||
else:
|
||||
raise ValueError(f'bad value for {init=}')
|
||||
|
||||
global_alignment_loop(self, **kw)
|
||||
|
||||
@torch.no_grad()
|
||||
def mask_sky(self):
|
||||
res = deepcopy(self)
|
||||
for i in range(self.n_imgs):
|
||||
sky = segment_sky(self.imgs[i])
|
||||
res.im_conf[i][sky] = 0
|
||||
return res
|
||||
|
||||
def show(self, show_pw_cams=False, show_pw_pts3d=False, cam_size=None, **kw):
|
||||
viz = SceneViz()
|
||||
if self.imgs is None:
|
||||
colors = np.random.randint(0, 256, size=(self.n_imgs, 3))
|
||||
colors = list(map(tuple, colors.tolist()))
|
||||
for n in range(self.n_imgs):
|
||||
viz.add_pointcloud(self.get_pts3d()[n], colors[n], self.get_masks()[n])
|
||||
else:
|
||||
viz.add_pointcloud(self.get_pts3d(), self.imgs, self.get_masks())
|
||||
colors = np.random.randint(256, size=(self.n_imgs, 3))
|
||||
|
||||
# camera poses
|
||||
im_poses = to_numpy(self.get_im_poses())
|
||||
if cam_size is None:
|
||||
cam_size = auto_cam_size(im_poses)
|
||||
viz.add_cameras(im_poses, self.get_focals(), colors=colors,
|
||||
images=self.imgs, imsizes=self.imsizes, cam_size=cam_size)
|
||||
if show_pw_cams:
|
||||
pw_poses = self.get_pw_poses()
|
||||
viz.add_cameras(pw_poses, color=(192, 0, 192), cam_size=cam_size)
|
||||
|
||||
if show_pw_pts3d:
|
||||
pts = [geotrf(pw_poses[e], self.pred_i[edge_str(i, j)]) for e, (i, j) in enumerate(self.edges)]
|
||||
viz.add_pointcloud(pts, (128, 0, 128))
|
||||
|
||||
viz.show(**kw)
|
||||
return viz
|
||||
|
||||
|
||||
def global_alignment_loop(net, lr=0.01, niter=300, schedule='cosine', lr_min=1e-6, verbose=False):
|
||||
params = [p for p in net.parameters() if p.requires_grad]
|
||||
if not params:
|
||||
return net
|
||||
|
||||
if verbose:
|
||||
print([name for name, value in net.named_parameters() if value.requires_grad])
|
||||
|
||||
lr_base = lr
|
||||
optimizer = torch.optim.Adam(params, lr=lr, betas=(0.9, 0.9))
|
||||
|
||||
with tqdm.tqdm(total=niter) as bar:
|
||||
while bar.n < bar.total:
|
||||
t = bar.n / bar.total
|
||||
|
||||
if schedule == 'cosine':
|
||||
lr = cosine_schedule(t, lr_base, lr_min)
|
||||
elif schedule == 'linear':
|
||||
lr = linear_schedule(t, lr_base, lr_min)
|
||||
else:
|
||||
raise ValueError(f'bad lr {schedule=}')
|
||||
adjust_learning_rate_by_lr(optimizer, lr)
|
||||
|
||||
optimizer.zero_grad()
|
||||
loss = net()
|
||||
loss.backward()
|
||||
optimizer.step()
|
||||
loss = float(loss)
|
||||
bar.set_postfix_str(f'{lr=:g} loss={loss:g}')
|
||||
bar.update()
|
||||
@@ -0,0 +1,90 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# utility functions for global alignment
|
||||
# --------------------------------------------------------
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import numpy as np
|
||||
|
||||
|
||||
def edge_str(i, j):
|
||||
return f'{i}_{j}'
|
||||
|
||||
|
||||
def i_j_ij(ij):
|
||||
return edge_str(*ij), ij
|
||||
|
||||
|
||||
def edge_conf(conf_i, conf_j, edge):
|
||||
return float(conf_i[edge].mean() * conf_j[edge].mean())
|
||||
|
||||
|
||||
def compute_edge_scores(edges, conf_i, conf_j):
|
||||
return {(i, j): edge_conf(conf_i, conf_j, e) for e, (i, j) in edges}
|
||||
|
||||
|
||||
def NoGradParamDict(x):
|
||||
assert isinstance(x, dict)
|
||||
return nn.ParameterDict(x).requires_grad_(False)
|
||||
|
||||
|
||||
def get_imshapes(edges, pred_i, pred_j):
|
||||
n_imgs = max(max(e) for e in edges) + 1
|
||||
imshapes = [None] * n_imgs
|
||||
for e, (i, j) in enumerate(edges):
|
||||
shape_i = tuple(pred_i[e].shape[0:2])
|
||||
shape_j = tuple(pred_j[e].shape[0:2])
|
||||
if imshapes[i]:
|
||||
assert imshapes[i] == shape_i, f'incorrect shape for image {i}'
|
||||
if imshapes[j]:
|
||||
assert imshapes[j] == shape_j, f'incorrect shape for image {j}'
|
||||
imshapes[i] = shape_i
|
||||
imshapes[j] = shape_j
|
||||
return imshapes
|
||||
|
||||
|
||||
def get_conf_trf(mode):
|
||||
if mode == 'log':
|
||||
def conf_trf(x): return x.log()
|
||||
elif mode == 'sqrt':
|
||||
def conf_trf(x): return x.sqrt()
|
||||
elif mode == 'm1':
|
||||
def conf_trf(x): return x-1
|
||||
elif mode in ('id', 'none'):
|
||||
def conf_trf(x): return x
|
||||
else:
|
||||
raise ValueError(f'bad mode for {mode=}')
|
||||
return conf_trf
|
||||
|
||||
|
||||
def l2_dist(a, b, weight):
|
||||
return ((a - b).square().sum(dim=-1) * weight)
|
||||
|
||||
|
||||
def l1_dist(a, b, weight):
|
||||
return ((a - b).norm(dim=-1) * weight)
|
||||
|
||||
|
||||
ALL_DISTS = dict(l1=l1_dist, l2=l2_dist)
|
||||
|
||||
|
||||
def signed_log1p(x):
|
||||
sign = torch.sign(x)
|
||||
return sign * torch.log1p(torch.abs(x))
|
||||
|
||||
|
||||
def signed_expm1(x):
|
||||
sign = torch.sign(x)
|
||||
return sign * torch.expm1(torch.abs(x))
|
||||
|
||||
|
||||
def cosine_schedule(t, lr_start, lr_end):
|
||||
assert 0 <= t <= 1
|
||||
return lr_end + (lr_start - lr_end) * (1+np.cos(t * np.pi))/2
|
||||
|
||||
|
||||
def linear_schedule(t, lr_start, lr_end):
|
||||
assert 0 <= t <= 1
|
||||
return lr_start + (lr_end - lr_start) * t
|
||||
@@ -0,0 +1,313 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# Initialization functions for global alignment
|
||||
# --------------------------------------------------------
|
||||
# from functools import cache
|
||||
from functools import lru_cache as cache
|
||||
|
||||
import numpy as np
|
||||
import scipy.sparse as sp
|
||||
import torch
|
||||
import cv2
|
||||
import roma
|
||||
from tqdm import tqdm
|
||||
|
||||
from dust3r.utils.geometry import geotrf, inv, get_med_dist_between_poses
|
||||
from dust3r.post_process import estimate_focal_knowing_depth
|
||||
from dust3r.viz import to_numpy
|
||||
|
||||
from dust3r.cloud_opt.commons import edge_str, i_j_ij, compute_edge_scores
|
||||
|
||||
|
||||
@torch.no_grad()
|
||||
def init_from_known_poses(self, niter_PnP=10, min_conf_thr=3):
|
||||
device = self.device
|
||||
|
||||
# indices of known poses
|
||||
nkp, known_poses_msk, known_poses = get_known_poses(self)
|
||||
assert nkp == self.n_imgs, 'not all poses are known'
|
||||
|
||||
# get all focals
|
||||
nkf, _, im_focals = get_known_focals(self)
|
||||
assert nkf == self.n_imgs
|
||||
im_pp = self.get_principal_points()
|
||||
|
||||
best_depthmaps = {}
|
||||
# init all pairwise poses
|
||||
for e, (i, j) in enumerate(tqdm(self.edges)):
|
||||
i_j = edge_str(i, j)
|
||||
|
||||
# find relative pose for this pair
|
||||
P1 = torch.eye(4, device=device)
|
||||
msk = self.conf_i[i_j] > min(min_conf_thr, self.conf_i[i_j].min() - 0.1)
|
||||
_, P2 = fast_pnp(self.pred_j[i_j], float(im_focals[i].mean()),
|
||||
pp=im_pp[i], msk=msk, device=device, niter_PnP=niter_PnP)
|
||||
|
||||
# align the two predicted camera with the two gt cameras
|
||||
s, R, T = align_multiple_poses(torch.stack((P1, P2)), known_poses[[i, j]])
|
||||
# normally we have known_poses[i] ~= sRT_to_4x4(s,R,T,device) @ P1
|
||||
# and geotrf(sRT_to_4x4(1,R,T,device), s*P2[:3,3])
|
||||
self._set_pose(self.pw_poses, e, R, T, scale=s)
|
||||
|
||||
# remember if this is a good depthmap
|
||||
score = float(self.conf_i[i_j].mean())
|
||||
if score > best_depthmaps.get(i, (0,))[0]:
|
||||
best_depthmaps[i] = score, i_j, s
|
||||
|
||||
# init all image poses
|
||||
for n in range(self.n_imgs):
|
||||
assert known_poses_msk[n]
|
||||
_, i_j, scale = best_depthmaps[n]
|
||||
depth = self.pred_i[i_j][:, :, 2]
|
||||
self._set_depthmap(n, depth * scale)
|
||||
|
||||
|
||||
@torch.no_grad()
|
||||
def init_minimum_spanning_tree(self, **kw):
|
||||
""" Init all camera poses (image-wise and pairwise poses) given
|
||||
an initial set of pairwise estimations.
|
||||
"""
|
||||
device = self.device
|
||||
pts3d, _, im_focals, im_poses = minimum_spanning_tree(self.imshapes, self.edges,
|
||||
self.pred_i, self.pred_j, self.conf_i, self.conf_j, self.im_conf, self.min_conf_thr,
|
||||
device, has_im_poses=self.has_im_poses, **kw)
|
||||
|
||||
return init_from_pts3d(self, pts3d, im_focals, im_poses)
|
||||
|
||||
|
||||
def init_from_pts3d(self, pts3d, im_focals, im_poses):
|
||||
# init poses
|
||||
nkp, known_poses_msk, known_poses = get_known_poses(self)
|
||||
if nkp == 1:
|
||||
raise NotImplementedError("Would be simpler to just align everything afterwards on the single known pose")
|
||||
elif nkp > 1:
|
||||
# global rigid SE3 alignment
|
||||
s, R, T = align_multiple_poses(im_poses[known_poses_msk], known_poses[known_poses_msk])
|
||||
trf = sRT_to_4x4(s, R, T, device=known_poses.device)
|
||||
|
||||
# rotate everything
|
||||
im_poses = trf @ im_poses
|
||||
im_poses[:, :3, :3] /= s # undo scaling on the rotation part
|
||||
for img_pts3d in pts3d:
|
||||
img_pts3d[:] = geotrf(trf, img_pts3d)
|
||||
|
||||
# set all pairwise poses
|
||||
for e, (i, j) in enumerate(self.edges):
|
||||
i_j = edge_str(i, j)
|
||||
# compute transform that goes from cam to world
|
||||
s, R, T = rigid_points_registration(self.pred_i[i_j], pts3d[i], conf=self.conf_i[i_j])
|
||||
self._set_pose(self.pw_poses, e, R, T, scale=s)
|
||||
|
||||
# take into account the scale normalization
|
||||
s_factor = self.get_pw_norm_scale_factor()
|
||||
im_poses[:, :3, 3] *= s_factor # apply downscaling factor
|
||||
for img_pts3d in pts3d:
|
||||
img_pts3d *= s_factor
|
||||
|
||||
# init all image poses
|
||||
if self.has_im_poses:
|
||||
for i in range(self.n_imgs):
|
||||
cam2world = im_poses[i]
|
||||
depth = geotrf(inv(cam2world), pts3d[i])[..., 2]
|
||||
self._set_depthmap(i, depth)
|
||||
self._set_pose(self.im_poses, i, cam2world)
|
||||
if im_focals[i] is not None:
|
||||
self._set_focal(i, im_focals[i])
|
||||
|
||||
print(' init loss =', float(self()))
|
||||
|
||||
|
||||
def minimum_spanning_tree(imshapes, edges, pred_i, pred_j, conf_i, conf_j, im_conf, min_conf_thr,
|
||||
device, has_im_poses=True, niter_PnP=10):
|
||||
n_imgs = len(imshapes)
|
||||
sparse_graph = -dict_to_sparse_graph(compute_edge_scores(map(i_j_ij, edges), conf_i, conf_j))
|
||||
msp = sp.csgraph.minimum_spanning_tree(sparse_graph).tocoo()
|
||||
|
||||
# temp variable to store 3d points
|
||||
pts3d = [None] * len(imshapes)
|
||||
|
||||
todo = sorted(zip(-msp.data, msp.row, msp.col)) # sorted edges
|
||||
im_poses = [None] * n_imgs
|
||||
im_focals = [None] * n_imgs
|
||||
|
||||
# init with strongest edge
|
||||
score, i, j = todo.pop()
|
||||
print(f' init edge ({i}*,{j}*) {score=}')
|
||||
i_j = edge_str(i, j)
|
||||
pts3d[i] = pred_i[i_j].clone()
|
||||
pts3d[j] = pred_j[i_j].clone()
|
||||
done = {i, j}
|
||||
if has_im_poses:
|
||||
im_poses[i] = torch.eye(4, device=device)
|
||||
im_focals[i] = estimate_focal(pred_i[i_j])
|
||||
|
||||
# set initial pointcloud based on pairwise graph
|
||||
msp_edges = [(i, j)]
|
||||
while todo:
|
||||
# each time, predict the next one
|
||||
score, i, j = todo.pop()
|
||||
|
||||
if im_focals[i] is None:
|
||||
im_focals[i] = estimate_focal(pred_i[i_j])
|
||||
|
||||
if i in done:
|
||||
print(f' init edge ({i},{j}*) {score=}')
|
||||
assert j not in done
|
||||
# align pred[i] with pts3d[i], and then set j accordingly
|
||||
i_j = edge_str(i, j)
|
||||
s, R, T = rigid_points_registration(pred_i[i_j], pts3d[i], conf=conf_i[i_j])
|
||||
trf = sRT_to_4x4(s, R, T, device)
|
||||
pts3d[j] = geotrf(trf, pred_j[i_j])
|
||||
done.add(j)
|
||||
msp_edges.append((i, j))
|
||||
|
||||
if has_im_poses and im_poses[i] is None:
|
||||
im_poses[i] = sRT_to_4x4(1, R, T, device)
|
||||
|
||||
elif j in done:
|
||||
print(f' init edge ({i}*,{j}) {score=}')
|
||||
assert i not in done
|
||||
i_j = edge_str(i, j)
|
||||
s, R, T = rigid_points_registration(pred_j[i_j], pts3d[j], conf=conf_j[i_j])
|
||||
trf = sRT_to_4x4(s, R, T, device)
|
||||
pts3d[i] = geotrf(trf, pred_i[i_j])
|
||||
done.add(i)
|
||||
msp_edges.append((i, j))
|
||||
|
||||
if has_im_poses and im_poses[i] is None:
|
||||
im_poses[i] = sRT_to_4x4(1, R, T, device)
|
||||
else:
|
||||
# let's try again later
|
||||
todo.insert(0, (score, i, j))
|
||||
|
||||
if has_im_poses:
|
||||
# complete all missing informations
|
||||
pair_scores = list(sparse_graph.values()) # already negative scores: less is best
|
||||
edges_from_best_to_worse = np.array(list(sparse_graph.keys()))[np.argsort(pair_scores)]
|
||||
for i, j in edges_from_best_to_worse.tolist():
|
||||
if im_focals[i] is None:
|
||||
im_focals[i] = estimate_focal(pred_i[edge_str(i, j)])
|
||||
|
||||
for i in range(n_imgs):
|
||||
if im_poses[i] is None:
|
||||
msk = im_conf[i] > min_conf_thr
|
||||
res = fast_pnp(pts3d[i], im_focals[i], msk=msk, device=device, niter_PnP=niter_PnP)
|
||||
if res:
|
||||
im_focals[i], im_poses[i] = res
|
||||
if im_poses[i] is None:
|
||||
im_poses[i] = torch.eye(4, device=device)
|
||||
im_poses = torch.stack(im_poses)
|
||||
else:
|
||||
im_poses = im_focals = None
|
||||
|
||||
return pts3d, msp_edges, im_focals, im_poses
|
||||
|
||||
|
||||
def dict_to_sparse_graph(dic):
|
||||
n_imgs = max(max(e) for e in dic) + 1
|
||||
res = sp.dok_array((n_imgs, n_imgs))
|
||||
for edge, value in dic.items():
|
||||
res[edge] = value
|
||||
return res
|
||||
|
||||
|
||||
def rigid_points_registration(pts1, pts2, conf):
|
||||
R, T, s = roma.rigid_points_registration(
|
||||
pts1.reshape(-1, 3), pts2.reshape(-1, 3), weights=conf.ravel(), compute_scaling=True)
|
||||
return s, R, T # return un-scaled (R, T)
|
||||
|
||||
|
||||
def sRT_to_4x4(scale, R, T, device):
|
||||
trf = torch.eye(4, device=device)
|
||||
trf[:3, :3] = R * scale
|
||||
trf[:3, 3] = T.ravel() # doesn't need scaling
|
||||
return trf
|
||||
|
||||
|
||||
def estimate_focal(pts3d_i, pp=None):
|
||||
if pp is None:
|
||||
H, W, THREE = pts3d_i.shape
|
||||
assert THREE == 3
|
||||
pp = torch.tensor((W/2, H/2), device=pts3d_i.device)
|
||||
focal = estimate_focal_knowing_depth(pts3d_i.unsqueeze(0), pp.unsqueeze(
|
||||
0), focal_mode='weiszfeld', min_focal=0.5, max_focal=3.5).ravel()
|
||||
return float(focal)
|
||||
|
||||
|
||||
@cache
|
||||
def pixel_grid(H, W):
|
||||
return np.mgrid[:W, :H].T.astype(np.float32)
|
||||
|
||||
|
||||
def fast_pnp(pts3d, focal, msk, device, pp=None, niter_PnP=10):
|
||||
# extract camera poses and focals with RANSAC-PnP
|
||||
if msk.sum() < 4:
|
||||
return None # we need at least 4 points for PnP
|
||||
pts3d, msk = map(to_numpy, (pts3d, msk))
|
||||
|
||||
H, W, THREE = pts3d.shape
|
||||
assert THREE == 3
|
||||
pixels = pixel_grid(H, W)
|
||||
|
||||
if focal is None:
|
||||
S = max(W, H)
|
||||
tentative_focals = np.geomspace(S/2, S*3, 21)
|
||||
else:
|
||||
tentative_focals = [focal]
|
||||
|
||||
if pp is None:
|
||||
pp = (W/2, H/2)
|
||||
else:
|
||||
pp = to_numpy(pp)
|
||||
|
||||
best = 0,
|
||||
for focal in tentative_focals:
|
||||
K = np.float32([(focal, 0, pp[0]), (0, focal, pp[1]), (0, 0, 1)])
|
||||
|
||||
success, R, T, inliers = cv2.solvePnPRansac(pts3d[msk], pixels[msk], K, None,
|
||||
iterationsCount=niter_PnP, reprojectionError=5, flags=cv2.SOLVEPNP_SQPNP)
|
||||
if not success:
|
||||
continue
|
||||
|
||||
score = len(inliers)
|
||||
if success and score > best[0]:
|
||||
best = score, R, T, focal
|
||||
|
||||
if not best[0]:
|
||||
return None
|
||||
|
||||
_, R, T, best_focal = best
|
||||
R = cv2.Rodrigues(R)[0] # world to cam
|
||||
R, T = map(torch.from_numpy, (R, T))
|
||||
return best_focal, inv(sRT_to_4x4(1, R, T, device)) # cam to world
|
||||
|
||||
|
||||
def get_known_poses(self):
|
||||
if self.has_im_poses:
|
||||
known_poses_msk = torch.tensor([not (p.requires_grad) for p in self.im_poses])
|
||||
known_poses = self.get_im_poses()
|
||||
return known_poses_msk.sum(), known_poses_msk, known_poses
|
||||
else:
|
||||
return 0, None, None
|
||||
|
||||
|
||||
def get_known_focals(self):
|
||||
if self.has_im_poses:
|
||||
known_focal_msk = self.get_known_focal_mask()
|
||||
known_focals = self.get_focals()
|
||||
return known_focal_msk.sum(), known_focal_msk, known_focals
|
||||
else:
|
||||
return 0, None, None
|
||||
|
||||
|
||||
def align_multiple_poses(src_poses, target_poses):
|
||||
N = len(src_poses)
|
||||
assert src_poses.shape == target_poses.shape == (N, 4, 4)
|
||||
|
||||
def center_and_z(poses):
|
||||
eps = get_med_dist_between_poses(poses) / 100
|
||||
return torch.cat((poses[:, :3, 3], poses[:, :3, 3] + eps*poses[:, :3, 2]))
|
||||
R, T, s = roma.rigid_points_registration(center_and_z(src_poses), center_and_z(target_poses), compute_scaling=True)
|
||||
return s, R, T
|
||||
@@ -0,0 +1,248 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# Main class for the implementation of the global alignment
|
||||
# --------------------------------------------------------
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
|
||||
from dust3r.cloud_opt.base_opt import BasePCOptimizer
|
||||
from dust3r.utils.geometry import xy_grid, geotrf
|
||||
from dust3r.utils.device import to_cpu, to_numpy
|
||||
|
||||
|
||||
class PointCloudOptimizer(BasePCOptimizer):
|
||||
""" Optimize a global scene, given a list of pairwise observations.
|
||||
Graph node: images
|
||||
Graph edges: observations = (pred1, pred2)
|
||||
"""
|
||||
|
||||
def __init__(self, *args, optimize_pp=False, focal_break=20, **kwargs):
|
||||
super().__init__(*args, **kwargs)
|
||||
|
||||
self.has_im_poses = True # by definition of this class
|
||||
self.focal_break = focal_break
|
||||
|
||||
# adding thing to optimize
|
||||
self.im_depthmaps = nn.ParameterList(torch.randn(H, W)/10-3 for H, W in self.imshapes) # log(depth)
|
||||
self.im_poses = nn.ParameterList(self.rand_pose(self.POSE_DIM) for _ in range(self.n_imgs)) # camera poses
|
||||
self.im_focals = nn.ParameterList(torch.FloatTensor(
|
||||
[self.focal_break*np.log(max(H, W))]) for H, W in self.imshapes) # camera intrinsics
|
||||
self.im_pp = nn.ParameterList(torch.zeros((2,)) for _ in range(self.n_imgs)) # camera intrinsics
|
||||
self.im_pp.requires_grad_(optimize_pp)
|
||||
|
||||
self.imshape = self.imshapes[0]
|
||||
im_areas = [h*w for h, w in self.imshapes]
|
||||
self.max_area = max(im_areas)
|
||||
|
||||
# adding thing to optimize
|
||||
self.im_depthmaps = ParameterStack(self.im_depthmaps, is_param=True, fill=self.max_area)
|
||||
self.im_poses = ParameterStack(self.im_poses, is_param=True)
|
||||
self.im_focals = ParameterStack(self.im_focals, is_param=True)
|
||||
self.im_pp = ParameterStack(self.im_pp, is_param=True)
|
||||
self.register_buffer('_pp', torch.tensor([(w/2, h/2) for h, w in self.imshapes]))
|
||||
self.register_buffer('_grid', ParameterStack(
|
||||
[xy_grid(W, H, device=self.device) for H, W in self.imshapes], fill=self.max_area))
|
||||
|
||||
# pre-compute pixel weights
|
||||
self.register_buffer('_weight_i', ParameterStack(
|
||||
[self.conf_trf(self.conf_i[i_j]) for i_j in self.str_edges], fill=self.max_area))
|
||||
self.register_buffer('_weight_j', ParameterStack(
|
||||
[self.conf_trf(self.conf_j[i_j]) for i_j in self.str_edges], fill=self.max_area))
|
||||
|
||||
# precompute aa
|
||||
self.register_buffer('_stacked_pred_i', ParameterStack(self.pred_i, self.str_edges, fill=self.max_area))
|
||||
self.register_buffer('_stacked_pred_j', ParameterStack(self.pred_j, self.str_edges, fill=self.max_area))
|
||||
self.register_buffer('_ei', torch.tensor([i for i, j in self.edges]))
|
||||
self.register_buffer('_ej', torch.tensor([j for i, j in self.edges]))
|
||||
self.total_area_i = sum([im_areas[i] for i, j in self.edges])
|
||||
self.total_area_j = sum([im_areas[j] for i, j in self.edges])
|
||||
|
||||
def _check_all_imgs_are_selected(self, msk):
|
||||
assert np.all(self._get_msk_indices(msk) == np.arange(self.n_imgs)), 'incomplete mask!'
|
||||
|
||||
def preset_pose(self, known_poses, pose_msk=None): # cam-to-world
|
||||
self._check_all_imgs_are_selected(pose_msk)
|
||||
|
||||
if isinstance(known_poses, torch.Tensor) and known_poses.ndim == 2:
|
||||
known_poses = [known_poses]
|
||||
for idx, pose in zip(self._get_msk_indices(pose_msk), known_poses):
|
||||
print(f' (setting pose #{idx} = {pose[:3,3]})')
|
||||
self._no_grad(self._set_pose(self.im_poses, idx, torch.tensor(pose)))
|
||||
|
||||
# normalize scale if there's less than 1 known pose
|
||||
n_known_poses = sum((p.requires_grad is False) for p in self.im_poses)
|
||||
self.norm_pw_scale = (n_known_poses <= 1)
|
||||
|
||||
self.im_poses.requires_grad_(False)
|
||||
self.norm_pw_scale = False
|
||||
|
||||
def preset_focal(self, known_focals, msk=None):
|
||||
self._check_all_imgs_are_selected(msk)
|
||||
|
||||
for idx, focal in zip(self._get_msk_indices(msk), known_focals):
|
||||
print(f' (setting focal #{idx} = {focal})')
|
||||
self._no_grad(self._set_focal(idx, focal))
|
||||
|
||||
self.im_focals.requires_grad_(False)
|
||||
|
||||
def preset_principal_point(self, known_pp, msk=None):
|
||||
self._check_all_imgs_are_selected(msk)
|
||||
|
||||
for idx, pp in zip(self._get_msk_indices(msk), known_pp):
|
||||
print(f' (setting principal point #{idx} = {pp})')
|
||||
self._no_grad(self._set_principal_point(idx, pp))
|
||||
|
||||
self.im_pp.requires_grad_(False)
|
||||
|
||||
def _get_msk_indices(self, msk):
|
||||
if msk is None:
|
||||
return range(self.n_imgs)
|
||||
elif isinstance(msk, int):
|
||||
return [msk]
|
||||
elif isinstance(msk, (tuple, list)):
|
||||
return self._get_msk_indices(np.array(msk))
|
||||
elif msk.dtype in (bool, torch.bool, np.bool_):
|
||||
assert len(msk) == self.n_imgs
|
||||
return np.cumsum([0] + msk.tolist())
|
||||
elif np.issubdtype(msk.dtype, np.integer):
|
||||
return msk
|
||||
else:
|
||||
raise ValueError(f'bad {msk=}')
|
||||
|
||||
def _no_grad(self, tensor):
|
||||
assert tensor.requires_grad, 'it must be True at this point, otherwise no modification occurs'
|
||||
|
||||
def _set_focal(self, idx, focal, force=False):
|
||||
param = self.im_focals[idx]
|
||||
if param.requires_grad or force: # can only init a parameter not already initialized
|
||||
param.data[:] = self.focal_break * np.log(focal)
|
||||
return param
|
||||
|
||||
def get_focals(self):
|
||||
log_focals = torch.stack(list(self.im_focals), dim=0)
|
||||
return (log_focals / self.focal_break).exp()
|
||||
|
||||
def get_known_focal_mask(self):
|
||||
return torch.tensor([not (p.requires_grad) for p in self.im_focals])
|
||||
|
||||
def _set_principal_point(self, idx, pp, force=False):
|
||||
param = self.im_pp[idx]
|
||||
H, W = self.imshapes[idx]
|
||||
if param.requires_grad or force: # can only init a parameter not already initialized
|
||||
param.data[:] = to_cpu(to_numpy(pp) - (W/2, H/2)) / 10
|
||||
return param
|
||||
|
||||
def get_principal_points(self):
|
||||
return self._pp + 10 * self.im_pp
|
||||
|
||||
def get_intrinsics(self):
|
||||
K = torch.zeros((self.n_imgs, 3, 3), device=self.device)
|
||||
focals = self.get_focals().flatten()
|
||||
K[:, 0, 0] = K[:, 1, 1] = focals
|
||||
K[:, :2, 2] = self.get_principal_points()
|
||||
K[:, 2, 2] = 1
|
||||
return K
|
||||
|
||||
def get_im_poses(self): # cam to world
|
||||
cam2world = self._get_poses(self.im_poses)
|
||||
return cam2world
|
||||
|
||||
def _set_depthmap(self, idx, depth, force=False):
|
||||
depth = _ravel_hw(depth, self.max_area)
|
||||
|
||||
param = self.im_depthmaps[idx]
|
||||
if param.requires_grad or force: # can only init a parameter not already initialized
|
||||
param.data[:] = depth.log().nan_to_num(neginf=0)
|
||||
return param
|
||||
|
||||
def get_depthmaps(self, raw=False, clip_thred = None):
|
||||
res = self.im_depthmaps.exp()
|
||||
if not raw:
|
||||
res = [dm[:h*w].view(h, w) for dm, (h, w) in zip(res, self.imshapes)]
|
||||
if clip_thred is not None:
|
||||
thred = torch.max(res)*clip_thred
|
||||
res = torch.where(res > thred, thred, res)
|
||||
return res
|
||||
|
||||
def depth_to_pts3d(self,clip_thred=None):
|
||||
# Get depths and projection params if not provided
|
||||
focals = self.get_focals()
|
||||
pp = self.get_principal_points()
|
||||
im_poses = self.get_im_poses()
|
||||
depth = self.get_depthmaps(raw=True,clip_thred = clip_thred)
|
||||
|
||||
# get pointmaps in camera frame
|
||||
rel_ptmaps = _fast_depthmap_to_pts3d(depth, self._grid, focals, pp=pp)
|
||||
# project to world frame
|
||||
return geotrf(im_poses, rel_ptmaps)
|
||||
|
||||
def get_pts3d(self, raw=False, clip_thred=None):
|
||||
res = self.depth_to_pts3d(clip_thred)
|
||||
if not raw:
|
||||
res = [dm[:h*w].view(h, w, 3) for dm, (h, w) in zip(res, self.imshapes)]
|
||||
return res
|
||||
|
||||
def forward(self):
|
||||
pw_poses = self.get_pw_poses() # cam-to-world
|
||||
pw_adapt = self.get_adaptors().unsqueeze(1)
|
||||
proj_pts3d = self.get_pts3d(raw=True)
|
||||
|
||||
# rotate pairwise prediction according to pw_poses
|
||||
aligned_pred_i = geotrf(pw_poses, pw_adapt * self._stacked_pred_i)
|
||||
aligned_pred_j = geotrf(pw_poses, pw_adapt * self._stacked_pred_j)
|
||||
|
||||
# compute the less
|
||||
li = self.dist(proj_pts3d[self._ei], aligned_pred_i, weight=self._weight_i).sum() / self.total_area_i
|
||||
lj = self.dist(proj_pts3d[self._ej], aligned_pred_j, weight=self._weight_j).sum() / self.total_area_j
|
||||
|
||||
return li + lj
|
||||
|
||||
|
||||
def _fast_depthmap_to_pts3d(depth, pixel_grid, focal, pp):
|
||||
pp = pp.unsqueeze(1)
|
||||
focal = focal.unsqueeze(1)
|
||||
assert focal.shape == (len(depth), 1, 1)
|
||||
assert pp.shape == (len(depth), 1, 2)
|
||||
assert pixel_grid.shape == depth.shape + (2,)
|
||||
depth = depth.unsqueeze(-1)
|
||||
return torch.cat((depth * (pixel_grid - pp) / focal, depth), dim=-1)
|
||||
|
||||
|
||||
def ParameterStack(params, keys=None, is_param=None, fill=0):
|
||||
if keys is not None:
|
||||
params = [params[k] for k in keys]
|
||||
|
||||
if fill > 0:
|
||||
params = [_ravel_hw(p, fill) for p in params]
|
||||
|
||||
requires_grad = params[0].requires_grad
|
||||
assert all(p.requires_grad == requires_grad for p in params)
|
||||
|
||||
params = torch.stack(list(params)).float().detach()
|
||||
if is_param or requires_grad:
|
||||
params = nn.Parameter(params)
|
||||
params.requires_grad_(requires_grad)
|
||||
return params
|
||||
|
||||
|
||||
def _ravel_hw(tensor, fill=0):
|
||||
# ravel H,W
|
||||
tensor = tensor.view((tensor.shape[0] * tensor.shape[1],) + tensor.shape[2:])
|
||||
|
||||
if len(tensor) < fill:
|
||||
tensor = torch.cat((tensor, tensor.new_zeros((fill - len(tensor),)+tensor.shape[1:])))
|
||||
return tensor
|
||||
|
||||
|
||||
def acceptable_focal_range(H, W, minf=0.5, maxf=3.5):
|
||||
focal_base = max(H, W) / (2 * np.tan(np.deg2rad(60) / 2)) # size / 1.1547005383792515
|
||||
return minf*focal_base, maxf*focal_base
|
||||
|
||||
|
||||
def apply_mask(img, msk):
|
||||
img = img.copy()
|
||||
img[msk] = 0
|
||||
return img
|
||||
@@ -0,0 +1,125 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# Dummy optimizer for visualizing pairs
|
||||
# --------------------------------------------------------
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import cv2
|
||||
|
||||
from dust3r.cloud_opt.base_opt import BasePCOptimizer
|
||||
from dust3r.utils.geometry import inv, geotrf, depthmap_to_absolute_camera_coordinates
|
||||
from dust3r.cloud_opt.commons import edge_str
|
||||
from dust3r.post_process import estimate_focal_knowing_depth
|
||||
|
||||
|
||||
class PairViewer (BasePCOptimizer):
|
||||
"""
|
||||
This a Dummy Optimizer.
|
||||
To use only when the goal is to visualize the results for a pair of images (with is_symmetrized)
|
||||
"""
|
||||
|
||||
def __init__(self, *args, **kwargs):
|
||||
super().__init__(*args, **kwargs)
|
||||
assert self.is_symmetrized and self.n_edges == 2
|
||||
self.has_im_poses = True
|
||||
|
||||
# compute all parameters directly from raw input
|
||||
self.focals = []
|
||||
self.pp = []
|
||||
rel_poses = []
|
||||
confs = []
|
||||
for i in range(self.n_imgs):
|
||||
conf = float(self.conf_i[edge_str(i, 1-i)].mean() * self.conf_j[edge_str(i, 1-i)].mean())
|
||||
print(f' - {conf=:.3} for edge {i}-{1-i}')
|
||||
confs.append(conf)
|
||||
|
||||
H, W = self.imshapes[i]
|
||||
pts3d = self.pred_i[edge_str(i, 1-i)]
|
||||
pp = torch.tensor((W/2, H/2))
|
||||
focal = float(estimate_focal_knowing_depth(pts3d[None], pp, focal_mode='weiszfeld'))
|
||||
self.focals.append(focal)
|
||||
self.pp.append(pp)
|
||||
|
||||
# estimate the pose of pts1 in image 2
|
||||
pixels = np.mgrid[:W, :H].T.astype(np.float32)
|
||||
pts3d = self.pred_j[edge_str(1-i, i)].numpy()
|
||||
assert pts3d.shape[:2] == (H, W)
|
||||
msk = self.get_masks()[i].numpy()
|
||||
K = np.float32([(focal, 0, pp[0]), (0, focal, pp[1]), (0, 0, 1)])
|
||||
|
||||
try:
|
||||
res = cv2.solvePnPRansac(pts3d[msk], pixels[msk], K, None,
|
||||
iterationsCount=100, reprojectionError=5, flags=cv2.SOLVEPNP_SQPNP)
|
||||
success, R, T, inliers = res
|
||||
assert success
|
||||
|
||||
R = cv2.Rodrigues(R)[0] # world to cam
|
||||
pose = inv(np.r_[np.c_[R, T], [(0, 0, 0, 1)]]) # cam to world
|
||||
except:
|
||||
pose = np.eye(4)
|
||||
rel_poses.append(torch.from_numpy(pose.astype(np.float32)))
|
||||
|
||||
# let's use the pair with the most confidence
|
||||
if confs[0] > confs[1]:
|
||||
# ptcloud is expressed in camera1
|
||||
self.im_poses = [torch.eye(4), rel_poses[1]] # I, cam2-to-cam1
|
||||
self.depth = [self.pred_i['0_1'][..., 2], geotrf(inv(rel_poses[1]), self.pred_j['0_1'])[..., 2]]
|
||||
else:
|
||||
# ptcloud is expressed in camera2
|
||||
self.im_poses = [rel_poses[0], torch.eye(4)] # I, cam1-to-cam2
|
||||
self.depth = [geotrf(inv(rel_poses[0]), self.pred_j['1_0'])[..., 2], self.pred_i['1_0'][..., 2]]
|
||||
|
||||
self.im_poses = nn.Parameter(torch.stack(self.im_poses, dim=0), requires_grad=False)
|
||||
self.focals = nn.Parameter(torch.tensor(self.focals), requires_grad=False)
|
||||
self.pp = nn.Parameter(torch.stack(self.pp, dim=0), requires_grad=False)
|
||||
self.depth = nn.ParameterList(self.depth)
|
||||
for p in self.parameters():
|
||||
p.requires_grad = False
|
||||
|
||||
def _set_depthmap(self, idx, depth, force=False):
|
||||
print('_set_depthmap is ignored in PairViewer')
|
||||
return
|
||||
|
||||
def get_depthmaps(self, raw=False):
|
||||
depth = [d.to(self.device) for d in self.depth]
|
||||
return depth
|
||||
|
||||
def _set_focal(self, idx, focal, force=False):
|
||||
self.focals[idx] = focal
|
||||
|
||||
def get_focals(self):
|
||||
return self.focals
|
||||
|
||||
def get_known_focal_mask(self):
|
||||
return torch.tensor([not (p.requires_grad) for p in self.focals])
|
||||
|
||||
def get_principal_points(self):
|
||||
return self.pp
|
||||
|
||||
def get_intrinsics(self):
|
||||
focals = self.get_focals()
|
||||
pps = self.get_principal_points()
|
||||
K = torch.zeros((len(focals), 3, 3), device=self.device)
|
||||
for i in range(len(focals)):
|
||||
K[i, 0, 0] = K[i, 1, 1] = focals[i]
|
||||
K[i, :2, 2] = pps[i]
|
||||
K[i, 2, 2] = 1
|
||||
return K
|
||||
|
||||
def get_im_poses(self):
|
||||
return self.im_poses
|
||||
|
||||
def depth_to_pts3d(self):
|
||||
pts3d = []
|
||||
for d, intrinsics, im_pose in zip(self.depth, self.get_intrinsics(), self.get_im_poses()):
|
||||
pts, _ = depthmap_to_absolute_camera_coordinates(d.cpu().numpy(),
|
||||
intrinsics.cpu().numpy(),
|
||||
im_pose.cpu().numpy())
|
||||
pts3d.append(torch.from_numpy(pts).to(device=self.device))
|
||||
return pts3d
|
||||
|
||||
def forward(self):
|
||||
return float('nan')
|
||||
@@ -0,0 +1,42 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
from .utils.transforms import *
|
||||
from .base.batched_sampler import BatchedRandomSampler # noqa: F401
|
||||
from .co3d import Co3d # noqa: F401
|
||||
|
||||
|
||||
def get_data_loader(dataset, batch_size, num_workers=8, shuffle=True, drop_last=True, pin_mem=True):
|
||||
import torch
|
||||
from croco.utils.misc import get_world_size, get_rank
|
||||
|
||||
# pytorch dataset
|
||||
if isinstance(dataset, str):
|
||||
dataset = eval(dataset)
|
||||
|
||||
world_size = get_world_size()
|
||||
rank = get_rank()
|
||||
|
||||
try:
|
||||
sampler = dataset.make_sampler(batch_size, shuffle=shuffle, world_size=world_size,
|
||||
rank=rank, drop_last=drop_last)
|
||||
except (AttributeError, NotImplementedError):
|
||||
# not avail for this dataset
|
||||
if torch.distributed.is_initialized():
|
||||
sampler = torch.utils.data.DistributedSampler(
|
||||
dataset, num_replicas=world_size, rank=rank, shuffle=shuffle, drop_last=drop_last
|
||||
)
|
||||
elif shuffle:
|
||||
sampler = torch.utils.data.RandomSampler(dataset)
|
||||
else:
|
||||
sampler = torch.utils.data.SequentialSampler(dataset)
|
||||
|
||||
data_loader = torch.utils.data.DataLoader(
|
||||
dataset,
|
||||
sampler=sampler,
|
||||
batch_size=batch_size,
|
||||
num_workers=num_workers,
|
||||
pin_memory=pin_mem,
|
||||
drop_last=drop_last,
|
||||
)
|
||||
|
||||
return data_loader
|
||||
@@ -0,0 +1,2 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
@@ -0,0 +1,220 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# base class for implementing datasets
|
||||
# --------------------------------------------------------
|
||||
import PIL
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
from dust3r.datasets.base.easy_dataset import EasyDataset
|
||||
from dust3r.datasets.utils.transforms import ImgNorm
|
||||
from dust3r.utils.geometry import depthmap_to_absolute_camera_coordinates
|
||||
import dust3r.datasets.utils.cropping as cropping
|
||||
|
||||
|
||||
class BaseStereoViewDataset (EasyDataset):
|
||||
""" Define all basic options.
|
||||
|
||||
Usage:
|
||||
class MyDataset (BaseStereoViewDataset):
|
||||
def _get_views(self, idx, rng):
|
||||
# overload here
|
||||
views = []
|
||||
views.append(dict(img=, ...))
|
||||
return views
|
||||
"""
|
||||
|
||||
def __init__(self, *, # only keyword arguments
|
||||
split=None,
|
||||
resolution=None, # square_size or (width, height) or list of [(width,height), ...]
|
||||
transform=ImgNorm,
|
||||
aug_crop=False,
|
||||
seed=None):
|
||||
self.num_views = 2
|
||||
self.split = split
|
||||
self._set_resolutions(resolution)
|
||||
|
||||
self.transform = transform
|
||||
if isinstance(transform, str):
|
||||
transform = eval(transform)
|
||||
|
||||
self.aug_crop = aug_crop
|
||||
self.seed = seed
|
||||
|
||||
def __len__(self):
|
||||
return len(self.scenes)
|
||||
|
||||
def get_stats(self):
|
||||
return f"{len(self)} pairs"
|
||||
|
||||
def __repr__(self):
|
||||
resolutions_str = '['+';'.join(f'{w}x{h}' for w, h in self._resolutions)+']'
|
||||
return f"""{type(self).__name__}({self.get_stats()},
|
||||
{self.split=},
|
||||
{self.seed=},
|
||||
resolutions={resolutions_str},
|
||||
{self.transform=})""".replace('self.', '').replace('\n', '').replace(' ', '')
|
||||
|
||||
def _get_views(self, idx, resolution, rng):
|
||||
raise NotImplementedError()
|
||||
|
||||
def __getitem__(self, idx):
|
||||
if isinstance(idx, tuple):
|
||||
# the idx is specifying the aspect-ratio
|
||||
idx, ar_idx = idx
|
||||
else:
|
||||
assert len(self._resolutions) == 1
|
||||
ar_idx = 0
|
||||
|
||||
# set-up the rng
|
||||
if self.seed: # reseed for each __getitem__
|
||||
self._rng = np.random.default_rng(seed=self.seed + idx)
|
||||
elif not hasattr(self, '_rng'):
|
||||
seed = torch.initial_seed() # this is different for each dataloader process
|
||||
self._rng = np.random.default_rng(seed=seed)
|
||||
|
||||
# over-loaded code
|
||||
resolution = self._resolutions[ar_idx] # DO NOT CHANGE THIS (compatible with BatchedRandomSampler)
|
||||
views = self._get_views(idx, resolution, self._rng)
|
||||
assert len(views) == self.num_views
|
||||
|
||||
# check data-types
|
||||
for v, view in enumerate(views):
|
||||
assert 'pts3d' not in view, f"pts3d should not be there, they will be computed afterwards based on intrinsics+depthmap for view {view_name(view)}"
|
||||
view['idx'] = (idx, ar_idx, v)
|
||||
|
||||
# encode the image
|
||||
width, height = view['img'].size
|
||||
view['true_shape'] = np.int32((height, width))
|
||||
view['img'] = self.transform(view['img'])
|
||||
|
||||
assert 'camera_intrinsics' in view
|
||||
if 'camera_pose' not in view:
|
||||
view['camera_pose'] = np.full((4, 4), np.nan, dtype=np.float32)
|
||||
else:
|
||||
assert np.isfinite(view['camera_pose']).all(), f'NaN in camera pose for view {view_name(view)}'
|
||||
assert 'pts3d' not in view
|
||||
assert 'valid_mask' not in view
|
||||
assert np.isfinite(view['depthmap']).all(), f'NaN in depthmap for view {view_name(view)}'
|
||||
pts3d, valid_mask = depthmap_to_absolute_camera_coordinates(**view)
|
||||
|
||||
view['pts3d'] = pts3d
|
||||
view['valid_mask'] = valid_mask & np.isfinite(pts3d).all(axis=-1)
|
||||
|
||||
# check all datatypes
|
||||
for key, val in view.items():
|
||||
res, err_msg = is_good_type(key, val)
|
||||
assert res, f"{err_msg} with {key}={val} for view {view_name(view)}"
|
||||
K = view['camera_intrinsics']
|
||||
|
||||
# last thing done!
|
||||
for view in views:
|
||||
# transpose to make sure all views are the same size
|
||||
transpose_to_landscape(view)
|
||||
# this allows to check whether the RNG is is the same state each time
|
||||
view['rng'] = int.from_bytes(self._rng.bytes(4), 'big')
|
||||
return views
|
||||
|
||||
def _set_resolutions(self, resolutions):
|
||||
assert resolutions is not None, 'undefined resolution'
|
||||
|
||||
if not isinstance(resolutions, list):
|
||||
resolutions = [resolutions]
|
||||
|
||||
self._resolutions = []
|
||||
for resolution in resolutions:
|
||||
if isinstance(resolution, int):
|
||||
width = height = resolution
|
||||
else:
|
||||
width, height = resolution
|
||||
assert isinstance(width, int), f'Bad type for {width=} {type(width)=}, should be int'
|
||||
assert isinstance(height, int), f'Bad type for {height=} {type(height)=}, should be int'
|
||||
assert width >= height
|
||||
self._resolutions.append((width, height))
|
||||
|
||||
def _crop_resize_if_necessary(self, image, depthmap, intrinsics, resolution, rng=None, info=None):
|
||||
""" This function:
|
||||
- first downsizes the image with LANCZOS inteprolation,
|
||||
which is better than bilinear interpolation in
|
||||
"""
|
||||
if not isinstance(image, PIL.Image.Image):
|
||||
image = PIL.Image.fromarray(image)
|
||||
|
||||
# downscale with lanczos interpolation so that image.size == resolution
|
||||
# cropping centered on the principal point
|
||||
W, H = image.size
|
||||
cx, cy = intrinsics[:2, 2].round().astype(int)
|
||||
min_margin_x = min(cx, W-cx)
|
||||
min_margin_y = min(cy, H-cy)
|
||||
assert min_margin_x > W/5, f'Bad principal point in view={info}'
|
||||
assert min_margin_y > H/5, f'Bad principal point in view={info}'
|
||||
# the new window will be a rectangle of size (2*min_margin_x, 2*min_margin_y) centered on (cx,cy)
|
||||
l, t = cx - min_margin_x, cy - min_margin_y
|
||||
r, b = cx + min_margin_x, cy + min_margin_y
|
||||
crop_bbox = (l, t, r, b)
|
||||
image, depthmap, intrinsics = cropping.crop_image_depthmap(image, depthmap, intrinsics, crop_bbox)
|
||||
|
||||
# transpose the resolution if necessary
|
||||
W, H = image.size # new size
|
||||
assert resolution[0] >= resolution[1]
|
||||
if H > 1.1*W:
|
||||
# image is portrait mode
|
||||
resolution = resolution[::-1]
|
||||
elif 0.9 < H/W < 1.1 and resolution[0] != resolution[1]:
|
||||
# image is square, so we chose (portrait, landscape) randomly
|
||||
if rng.integers(2):
|
||||
resolution = resolution[::-1]
|
||||
|
||||
# high-quality Lanczos down-scaling
|
||||
target_resolution = np.array(resolution)
|
||||
if self.aug_crop > 1:
|
||||
target_resolution += rng.integers(0, self.aug_crop)
|
||||
image, depthmap, intrinsics = cropping.rescale_image_depthmap(image, depthmap, intrinsics, target_resolution)
|
||||
|
||||
# actual cropping (if necessary) with bilinear interpolation
|
||||
intrinsics2 = cropping.camera_matrix_of_crop(intrinsics, image.size, resolution, offset_factor=0.5)
|
||||
crop_bbox = cropping.bbox_from_intrinsics_in_out(intrinsics, intrinsics2, resolution)
|
||||
image, depthmap, intrinsics2 = cropping.crop_image_depthmap(image, depthmap, intrinsics, crop_bbox)
|
||||
|
||||
return image, depthmap, intrinsics2
|
||||
|
||||
|
||||
def is_good_type(key, v):
|
||||
""" returns (is_good, err_msg)
|
||||
"""
|
||||
if isinstance(v, (str, int, tuple)):
|
||||
return True, None
|
||||
if v.dtype not in (np.float32, torch.float32, bool, np.int32, np.int64, np.uint8):
|
||||
return False, f"bad {v.dtype=}"
|
||||
return True, None
|
||||
|
||||
|
||||
def view_name(view, batch_index=None):
|
||||
def sel(x): return x[batch_index] if batch_index not in (None, slice(None)) else x
|
||||
db = sel(view['dataset'])
|
||||
label = sel(view['label'])
|
||||
instance = sel(view['instance'])
|
||||
return f"{db}/{label}/{instance}"
|
||||
|
||||
|
||||
def transpose_to_landscape(view):
|
||||
height, width = view['true_shape']
|
||||
|
||||
if width < height:
|
||||
# rectify portrait to landscape
|
||||
assert view['img'].shape == (3, height, width)
|
||||
view['img'] = view['img'].swapaxes(1, 2)
|
||||
|
||||
assert view['valid_mask'].shape == (height, width)
|
||||
view['valid_mask'] = view['valid_mask'].swapaxes(0, 1)
|
||||
|
||||
assert view['depthmap'].shape == (height, width)
|
||||
view['depthmap'] = view['depthmap'].swapaxes(0, 1)
|
||||
|
||||
assert view['pts3d'].shape == (height, width, 3)
|
||||
view['pts3d'] = view['pts3d'].swapaxes(0, 1)
|
||||
|
||||
# transpose x and y pixels
|
||||
view['camera_intrinsics'] = view['camera_intrinsics'][[1, 0, 2]]
|
||||
@@ -0,0 +1,74 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# Random sampling under a constraint
|
||||
# --------------------------------------------------------
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
|
||||
class BatchedRandomSampler:
|
||||
""" Random sampling under a constraint: each sample in the batch has the same feature,
|
||||
which is chosen randomly from a known pool of 'features' for each batch.
|
||||
|
||||
For instance, the 'feature' could be the image aspect-ratio.
|
||||
|
||||
The index returned is a tuple (sample_idx, feat_idx).
|
||||
This sampler ensures that each series of `batch_size` indices has the same `feat_idx`.
|
||||
"""
|
||||
|
||||
def __init__(self, dataset, batch_size, pool_size, world_size=1, rank=0, drop_last=True):
|
||||
self.batch_size = batch_size
|
||||
self.pool_size = pool_size
|
||||
|
||||
self.len_dataset = N = len(dataset)
|
||||
self.total_size = round_by(N, batch_size*world_size) if drop_last else N
|
||||
assert world_size == 1 or drop_last, 'must drop the last batch in distributed mode'
|
||||
|
||||
# distributed sampler
|
||||
self.world_size = world_size
|
||||
self.rank = rank
|
||||
self.epoch = None
|
||||
|
||||
def __len__(self):
|
||||
return self.total_size // self.world_size
|
||||
|
||||
def set_epoch(self, epoch):
|
||||
self.epoch = epoch
|
||||
|
||||
def __iter__(self):
|
||||
# prepare RNG
|
||||
if self.epoch is None:
|
||||
assert self.world_size == 1 and self.rank == 0, 'use set_epoch() if distributed mode is used'
|
||||
seed = int(torch.empty((), dtype=torch.int64).random_().item())
|
||||
else:
|
||||
seed = self.epoch + 777
|
||||
rng = np.random.default_rng(seed=seed)
|
||||
|
||||
# random indices (will restart from 0 if not drop_last)
|
||||
sample_idxs = np.arange(self.total_size)
|
||||
rng.shuffle(sample_idxs)
|
||||
|
||||
# random feat_idxs (same across each batch)
|
||||
n_batches = (self.total_size+self.batch_size-1) // self.batch_size
|
||||
feat_idxs = rng.integers(self.pool_size, size=n_batches)
|
||||
feat_idxs = np.broadcast_to(feat_idxs[:, None], (n_batches, self.batch_size))
|
||||
feat_idxs = feat_idxs.ravel()[:self.total_size]
|
||||
|
||||
# put them together
|
||||
idxs = np.c_[sample_idxs, feat_idxs] # shape = (total_size, 2)
|
||||
|
||||
# Distributed sampler: we select a subset of batches
|
||||
# make sure the slice for each node is aligned with batch_size
|
||||
size_per_proc = self.batch_size * ((self.total_size + self.world_size *
|
||||
self.batch_size-1) // (self.world_size * self.batch_size))
|
||||
idxs = idxs[self.rank*size_per_proc: (self.rank+1)*size_per_proc]
|
||||
|
||||
yield from (tuple(idx) for idx in idxs)
|
||||
|
||||
|
||||
def round_by(total, multiple, up=False):
|
||||
if up:
|
||||
total = total + multiple-1
|
||||
return (total//multiple) * multiple
|
||||
@@ -0,0 +1,157 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# A dataset base class that you can easily resize and combine.
|
||||
# --------------------------------------------------------
|
||||
import numpy as np
|
||||
from dust3r.datasets.base.batched_sampler import BatchedRandomSampler
|
||||
|
||||
|
||||
class EasyDataset:
|
||||
""" a dataset that you can easily resize and combine.
|
||||
Examples:
|
||||
---------
|
||||
2 * dataset ==> duplicate each element 2x
|
||||
|
||||
10 @ dataset ==> set the size to 10 (random sampling, duplicates if necessary)
|
||||
|
||||
dataset1 + dataset2 ==> concatenate datasets
|
||||
"""
|
||||
|
||||
def __add__(self, other):
|
||||
return CatDataset([self, other])
|
||||
|
||||
def __rmul__(self, factor):
|
||||
return MulDataset(factor, self)
|
||||
|
||||
def __rmatmul__(self, factor):
|
||||
return ResizedDataset(factor, self)
|
||||
|
||||
def set_epoch(self, epoch):
|
||||
pass # nothing to do by default
|
||||
|
||||
def make_sampler(self, batch_size, shuffle=True, world_size=1, rank=0, drop_last=True):
|
||||
if not (shuffle):
|
||||
raise NotImplementedError() # cannot deal yet
|
||||
num_of_aspect_ratios = len(self._resolutions)
|
||||
return BatchedRandomSampler(self, batch_size, num_of_aspect_ratios, world_size=world_size, rank=rank, drop_last=drop_last)
|
||||
|
||||
|
||||
class MulDataset (EasyDataset):
|
||||
""" Artifically augmenting the size of a dataset.
|
||||
"""
|
||||
multiplicator: int
|
||||
|
||||
def __init__(self, multiplicator, dataset):
|
||||
assert isinstance(multiplicator, int) and multiplicator > 0
|
||||
self.multiplicator = multiplicator
|
||||
self.dataset = dataset
|
||||
|
||||
def __len__(self):
|
||||
return self.multiplicator * len(self.dataset)
|
||||
|
||||
def __repr__(self):
|
||||
return f'{self.multiplicator}*{repr(self.dataset)}'
|
||||
|
||||
def __getitem__(self, idx):
|
||||
if isinstance(idx, tuple):
|
||||
idx, other = idx
|
||||
return self.dataset[idx // self.multiplicator, other]
|
||||
else:
|
||||
return self.dataset[idx // self.multiplicator]
|
||||
|
||||
@property
|
||||
def _resolutions(self):
|
||||
return self.dataset._resolutions
|
||||
|
||||
|
||||
class ResizedDataset (EasyDataset):
|
||||
""" Artifically changing the size of a dataset.
|
||||
"""
|
||||
new_size: int
|
||||
|
||||
def __init__(self, new_size, dataset):
|
||||
assert isinstance(new_size, int) and new_size > 0
|
||||
self.new_size = new_size
|
||||
self.dataset = dataset
|
||||
|
||||
def __len__(self):
|
||||
return self.new_size
|
||||
|
||||
def __repr__(self):
|
||||
size_str = str(self.new_size)
|
||||
for i in range((len(size_str)-1) // 3):
|
||||
sep = -4*i-3
|
||||
size_str = size_str[:sep] + '_' + size_str[sep:]
|
||||
return f'{size_str} @ {repr(self.dataset)}'
|
||||
|
||||
def set_epoch(self, epoch):
|
||||
# this random shuffle only depends on the epoch
|
||||
rng = np.random.default_rng(seed=epoch+777)
|
||||
|
||||
# shuffle all indices
|
||||
perm = rng.permutation(len(self.dataset))
|
||||
|
||||
# rotary extension until target size is met
|
||||
shuffled_idxs = np.concatenate([perm] * (1 + (len(self)-1) // len(self.dataset)))
|
||||
self._idxs_mapping = shuffled_idxs[:self.new_size]
|
||||
|
||||
assert len(self._idxs_mapping) == self.new_size
|
||||
|
||||
def __getitem__(self, idx):
|
||||
assert hasattr(self, '_idxs_mapping'), 'You need to call dataset.set_epoch() to use ResizedDataset.__getitem__()'
|
||||
if isinstance(idx, tuple):
|
||||
idx, other = idx
|
||||
return self.dataset[self._idxs_mapping[idx], other]
|
||||
else:
|
||||
return self.dataset[self._idxs_mapping[idx]]
|
||||
|
||||
@property
|
||||
def _resolutions(self):
|
||||
return self.dataset._resolutions
|
||||
|
||||
|
||||
class CatDataset (EasyDataset):
|
||||
""" Concatenation of several datasets
|
||||
"""
|
||||
|
||||
def __init__(self, datasets):
|
||||
for dataset in datasets:
|
||||
assert isinstance(dataset, EasyDataset)
|
||||
self.datasets = datasets
|
||||
self._cum_sizes = np.cumsum([len(dataset) for dataset in datasets])
|
||||
|
||||
def __len__(self):
|
||||
return self._cum_sizes[-1]
|
||||
|
||||
def __repr__(self):
|
||||
# remove uselessly long transform
|
||||
return ' + '.join(repr(dataset).replace(',transform=Compose( ToTensor() Normalize(mean=(0.5, 0.5, 0.5), std=(0.5, 0.5, 0.5)))', '') for dataset in self.datasets)
|
||||
|
||||
def set_epoch(self, epoch):
|
||||
for dataset in self.datasets:
|
||||
dataset.set_epoch(epoch)
|
||||
|
||||
def __getitem__(self, idx):
|
||||
other = None
|
||||
if isinstance(idx, tuple):
|
||||
idx, other = idx
|
||||
|
||||
if not (0 <= idx < len(self)):
|
||||
raise IndexError()
|
||||
|
||||
db_idx = np.searchsorted(self._cum_sizes, idx, 'right')
|
||||
dataset = self.datasets[db_idx]
|
||||
new_idx = idx - (self._cum_sizes[db_idx - 1] if db_idx > 0 else 0)
|
||||
|
||||
if other is not None:
|
||||
new_idx = (new_idx, other)
|
||||
return dataset[new_idx]
|
||||
|
||||
@property
|
||||
def _resolutions(self):
|
||||
resolutions = self.datasets[0]._resolutions
|
||||
for dataset in self.datasets[1:]:
|
||||
assert tuple(dataset._resolutions) == tuple(resolutions)
|
||||
return resolutions
|
||||
+146
@@ -0,0 +1,146 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# Dataloader for preprocessed Co3d_v2
|
||||
# dataset at https://github.com/facebookresearch/co3d - Creative Commons Attribution-NonCommercial 4.0 International
|
||||
# See datasets_preprocess/preprocess_co3d.py
|
||||
# --------------------------------------------------------
|
||||
import os.path as osp
|
||||
import json
|
||||
import itertools
|
||||
from collections import deque
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
from dust3r.datasets.base.base_stereo_view_dataset import BaseStereoViewDataset
|
||||
from dust3r.utils.image import imread_cv2
|
||||
|
||||
|
||||
class Co3d(BaseStereoViewDataset):
|
||||
def __init__(self, mask_bg=True, *args, ROOT, **kwargs):
|
||||
self.ROOT = ROOT
|
||||
super().__init__(*args, **kwargs)
|
||||
assert mask_bg in (True, False, 'rand')
|
||||
self.mask_bg = mask_bg
|
||||
|
||||
# load all scenes
|
||||
with open(osp.join(self.ROOT, f'selected_seqs_{self.split}.json'), 'r') as f:
|
||||
self.scenes = json.load(f)
|
||||
self.scenes = {k: v for k, v in self.scenes.items() if len(v) > 0}
|
||||
self.scenes = {(k, k2): v2 for k, v in self.scenes.items()
|
||||
for k2, v2 in v.items()}
|
||||
self.scene_list = list(self.scenes.keys())
|
||||
|
||||
# for each scene, we have 100 images ==> 360 degrees (so 25 frames ~= 90 degrees)
|
||||
# we prepare all combinations such that i-j = +/- [5, 10, .., 90] degrees
|
||||
self.combinations = [(i, j)
|
||||
for i, j in itertools.combinations(range(100), 2)
|
||||
if 0 < abs(i-j) <= 30 and abs(i-j) % 5 == 0]
|
||||
|
||||
self.invalidate = {scene: {} for scene in self.scene_list}
|
||||
|
||||
def __len__(self):
|
||||
return len(self.scene_list) * len(self.combinations)
|
||||
|
||||
def _get_views(self, idx, resolution, rng):
|
||||
# choose a scene
|
||||
obj, instance = self.scene_list[idx // len(self.combinations)]
|
||||
image_pool = self.scenes[obj, instance]
|
||||
im1_idx, im2_idx = self.combinations[idx % len(self.combinations)]
|
||||
|
||||
# add a bit of randomness
|
||||
last = len(image_pool)-1
|
||||
|
||||
if resolution not in self.invalidate[obj, instance]: # flag invalid images
|
||||
self.invalidate[obj, instance][resolution] = [False for _ in range(len(image_pool))]
|
||||
|
||||
# decide now if we mask the bg
|
||||
mask_bg = (self.mask_bg == True) or (self.mask_bg == 'rand' and rng.choice(2))
|
||||
|
||||
views = []
|
||||
imgs_idxs = [max(0, min(im_idx + rng.integers(-4, 5), last)) for im_idx in [im2_idx, im1_idx]]
|
||||
imgs_idxs = deque(imgs_idxs)
|
||||
while len(imgs_idxs) > 0: # some images (few) have zero depth
|
||||
im_idx = imgs_idxs.pop()
|
||||
|
||||
if self.invalidate[obj, instance][resolution][im_idx]:
|
||||
# search for a valid image
|
||||
random_direction = 2 * rng.choice(2) - 1
|
||||
for offset in range(1, len(image_pool)):
|
||||
tentative_im_idx = (im_idx + (random_direction * offset)) % len(image_pool)
|
||||
if not self.invalidate[obj, instance][resolution][tentative_im_idx]:
|
||||
im_idx = tentative_im_idx
|
||||
break
|
||||
|
||||
view_idx = image_pool[im_idx]
|
||||
|
||||
impath = osp.join(self.ROOT, obj, instance, 'images', f'frame{view_idx:06n}.jpg')
|
||||
|
||||
# load camera params
|
||||
input_metadata = np.load(impath.replace('jpg', 'npz'))
|
||||
camera_pose = input_metadata['camera_pose'].astype(np.float32)
|
||||
intrinsics = input_metadata['camera_intrinsics'].astype(np.float32)
|
||||
|
||||
# load image and depth
|
||||
rgb_image = imread_cv2(impath)
|
||||
depthmap = imread_cv2(impath.replace('images', 'depths') + '.geometric.png', cv2.IMREAD_UNCHANGED)
|
||||
depthmap = (depthmap.astype(np.float32) / 65535) * np.nan_to_num(input_metadata['maximum_depth'])
|
||||
|
||||
if mask_bg:
|
||||
# load object mask
|
||||
maskpath = osp.join(self.ROOT, obj, instance, 'masks', f'frame{view_idx:06n}.png')
|
||||
maskmap = imread_cv2(maskpath, cv2.IMREAD_UNCHANGED).astype(np.float32)
|
||||
maskmap = (maskmap / 255.0) > 0.1
|
||||
|
||||
# update the depthmap with mask
|
||||
depthmap *= maskmap
|
||||
|
||||
rgb_image, depthmap, intrinsics = self._crop_resize_if_necessary(
|
||||
rgb_image, depthmap, intrinsics, resolution, rng=rng, info=impath)
|
||||
|
||||
num_valid = (depthmap > 0.0).sum()
|
||||
if num_valid == 0:
|
||||
# problem, invalidate image and retry
|
||||
self.invalidate[obj, instance][resolution][im_idx] = True
|
||||
imgs_idxs.append(im_idx)
|
||||
continue
|
||||
|
||||
views.append(dict(
|
||||
img=rgb_image,
|
||||
depthmap=depthmap,
|
||||
camera_pose=camera_pose,
|
||||
camera_intrinsics=intrinsics,
|
||||
dataset='Co3d_v2',
|
||||
label=osp.join(obj, instance),
|
||||
instance=osp.split(impath)[1],
|
||||
))
|
||||
return views
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
from dust3r.datasets.base.base_stereo_view_dataset import view_name
|
||||
from dust3r.viz import SceneViz, auto_cam_size
|
||||
from dust3r.utils.image import rgb
|
||||
|
||||
dataset = Co3d(split='train', ROOT="data/co3d_subset_processed", resolution=224, aug_crop=16)
|
||||
|
||||
for idx in np.random.permutation(len(dataset)):
|
||||
views = dataset[idx]
|
||||
assert len(views) == 2
|
||||
print(view_name(views[0]), view_name(views[1]))
|
||||
viz = SceneViz()
|
||||
poses = [views[view_idx]['camera_pose'] for view_idx in [0, 1]]
|
||||
cam_size = max(auto_cam_size(poses), 0.001)
|
||||
for view_idx in [0, 1]:
|
||||
pts3d = views[view_idx]['pts3d']
|
||||
valid_mask = views[view_idx]['valid_mask']
|
||||
colors = rgb(views[view_idx]['img'])
|
||||
viz.add_pointcloud(pts3d, colors, valid_mask)
|
||||
viz.add_camera(pose_c2w=views[view_idx]['camera_pose'],
|
||||
focal=views[view_idx]['camera_intrinsics'][0, 0],
|
||||
color=(idx*255, (1 - idx)*255, 0),
|
||||
image=colors,
|
||||
cam_size=cam_size)
|
||||
viz.show()
|
||||
@@ -0,0 +1,2 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
@@ -0,0 +1,119 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# croppping utilities
|
||||
# --------------------------------------------------------
|
||||
import PIL.Image
|
||||
import os
|
||||
os.environ["OPENCV_IO_ENABLE_OPENEXR"] = "1"
|
||||
import cv2 # noqa
|
||||
import numpy as np # noqa
|
||||
from dust3r.utils.geometry import colmap_to_opencv_intrinsics, opencv_to_colmap_intrinsics # noqa
|
||||
try:
|
||||
lanczos = PIL.Image.Resampling.LANCZOS
|
||||
except AttributeError:
|
||||
lanczos = PIL.Image.LANCZOS
|
||||
|
||||
|
||||
class ImageList:
|
||||
""" Convenience class to aply the same operation to a whole set of images.
|
||||
"""
|
||||
|
||||
def __init__(self, images):
|
||||
if not isinstance(images, (tuple, list, set)):
|
||||
images = [images]
|
||||
self.images = []
|
||||
for image in images:
|
||||
if not isinstance(image, PIL.Image.Image):
|
||||
image = PIL.Image.fromarray(image)
|
||||
self.images.append(image)
|
||||
|
||||
def __len__(self):
|
||||
return len(self.images)
|
||||
|
||||
def to_pil(self):
|
||||
return tuple(self.images) if len(self.images) > 1 else self.images[0]
|
||||
|
||||
@property
|
||||
def size(self):
|
||||
sizes = [im.size for im in self.images]
|
||||
assert all(sizes[0] == s for s in sizes)
|
||||
return sizes[0]
|
||||
|
||||
def resize(self, *args, **kwargs):
|
||||
return ImageList(self._dispatch('resize', *args, **kwargs))
|
||||
|
||||
def crop(self, *args, **kwargs):
|
||||
return ImageList(self._dispatch('crop', *args, **kwargs))
|
||||
|
||||
def _dispatch(self, func, *args, **kwargs):
|
||||
return [getattr(im, func)(*args, **kwargs) for im in self.images]
|
||||
|
||||
|
||||
def rescale_image_depthmap(image, depthmap, camera_intrinsics, output_resolution):
|
||||
""" Jointly rescale a (image, depthmap)
|
||||
so that (out_width, out_height) >= output_res
|
||||
"""
|
||||
image = ImageList(image)
|
||||
input_resolution = np.array(image.size) # (W,H)
|
||||
output_resolution = np.array(output_resolution)
|
||||
if depthmap is not None:
|
||||
# can also use this with masks instead of depthmaps
|
||||
assert tuple(depthmap.shape[:2]) == image.size[::-1]
|
||||
assert output_resolution.shape == (2,)
|
||||
# define output resolution
|
||||
scale_final = max(output_resolution / image.size) + 1e-8
|
||||
output_resolution = np.floor(input_resolution * scale_final).astype(int)
|
||||
|
||||
# first rescale the image so that it contains the crop
|
||||
image = image.resize(output_resolution, resample=lanczos)
|
||||
if depthmap is not None:
|
||||
depthmap = cv2.resize(depthmap, output_resolution, fx=scale_final,
|
||||
fy=scale_final, interpolation=cv2.INTER_NEAREST)
|
||||
|
||||
# no offset here; simple rescaling
|
||||
camera_intrinsics = camera_matrix_of_crop(
|
||||
camera_intrinsics, input_resolution, output_resolution, scaling=scale_final)
|
||||
|
||||
return image.to_pil(), depthmap, camera_intrinsics
|
||||
|
||||
|
||||
def camera_matrix_of_crop(input_camera_matrix, input_resolution, output_resolution, scaling=1, offset_factor=0.5, offset=None):
|
||||
# Margins to offset the origin
|
||||
margins = np.asarray(input_resolution) * scaling - output_resolution
|
||||
assert np.all(margins >= 0.0)
|
||||
if offset is None:
|
||||
offset = offset_factor * margins
|
||||
|
||||
# Generate new camera parameters
|
||||
output_camera_matrix_colmap = opencv_to_colmap_intrinsics(input_camera_matrix)
|
||||
output_camera_matrix_colmap[:2, :] *= scaling
|
||||
output_camera_matrix_colmap[:2, 2] -= offset
|
||||
output_camera_matrix = colmap_to_opencv_intrinsics(output_camera_matrix_colmap)
|
||||
|
||||
return output_camera_matrix
|
||||
|
||||
|
||||
def crop_image_depthmap(image, depthmap, camera_intrinsics, crop_bbox):
|
||||
"""
|
||||
Return a crop of the input view.
|
||||
"""
|
||||
image = ImageList(image)
|
||||
l, t, r, b = crop_bbox
|
||||
|
||||
image = image.crop((l, t, r, b))
|
||||
depthmap = depthmap[t:b, l:r]
|
||||
|
||||
camera_intrinsics = camera_intrinsics.copy()
|
||||
camera_intrinsics[0, 2] -= l
|
||||
camera_intrinsics[1, 2] -= t
|
||||
|
||||
return image.to_pil(), depthmap, camera_intrinsics
|
||||
|
||||
|
||||
def bbox_from_intrinsics_in_out(input_camera_matrix, output_camera_matrix, output_resolution):
|
||||
out_width, out_height = output_resolution
|
||||
l, t = np.int32(np.round(input_camera_matrix[:2, 2] - output_camera_matrix[:2, 2]))
|
||||
crop_bbox = (l, t, l+out_width, t+out_height)
|
||||
return crop_bbox
|
||||
@@ -0,0 +1,11 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# DUST3R default transforms
|
||||
# --------------------------------------------------------
|
||||
import torchvision.transforms as tvf
|
||||
from dust3r.utils.image import ImgNorm
|
||||
|
||||
# define the standard image transforms
|
||||
ColorJitter = tvf.Compose([tvf.ColorJitter(0.5, 0.5, 0.5, 0.1), ImgNorm])
|
||||
@@ -0,0 +1,19 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# head factory
|
||||
# --------------------------------------------------------
|
||||
from .linear_head import LinearPts3d
|
||||
from .dpt_head import create_dpt_head
|
||||
|
||||
|
||||
def head_factory(head_type, output_mode, net, has_conf=False):
|
||||
"""" build a prediction head for the decoder
|
||||
"""
|
||||
if head_type == 'linear' and output_mode == 'pts3d':
|
||||
return LinearPts3d(net, has_conf)
|
||||
elif head_type == 'dpt' and output_mode == 'pts3d':
|
||||
return create_dpt_head(net, has_conf=has_conf)
|
||||
else:
|
||||
raise NotImplementedError(f"unexpected {head_type=} and {output_mode=}")
|
||||
+115
@@ -0,0 +1,115 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# dpt head implementation for DUST3R
|
||||
# Downstream heads assume inputs of size B x N x C (where N is the number of tokens) ;
|
||||
# or if it takes as input the output at every layer, the attribute return_all_layers should be set to True
|
||||
# the forward function also takes as input a dictionnary img_info with key "height" and "width"
|
||||
# for PixelwiseTask, the output will be of dimension B x num_channels x H x W
|
||||
# --------------------------------------------------------
|
||||
from einops import rearrange
|
||||
from typing import List
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from dust3r.heads.postprocess import postprocess
|
||||
import dust3r.utils.path_to_croco # noqa: F401
|
||||
from models.dpt_block import DPTOutputAdapter # noqa
|
||||
|
||||
|
||||
class DPTOutputAdapter_fix(DPTOutputAdapter):
|
||||
"""
|
||||
Adapt croco's DPTOutputAdapter implementation for dust3r:
|
||||
remove duplicated weigths, and fix forward for dust3r
|
||||
"""
|
||||
|
||||
def init(self, dim_tokens_enc=768):
|
||||
super().init(dim_tokens_enc)
|
||||
# these are duplicated weights
|
||||
del self.act_1_postprocess
|
||||
del self.act_2_postprocess
|
||||
del self.act_3_postprocess
|
||||
del self.act_4_postprocess
|
||||
|
||||
def forward(self, encoder_tokens: List[torch.Tensor], image_size=None):
|
||||
assert self.dim_tokens_enc is not None, 'Need to call init(dim_tokens_enc) function first'
|
||||
# H, W = input_info['image_size']
|
||||
image_size = self.image_size if image_size is None else image_size
|
||||
H, W = image_size
|
||||
# Number of patches in height and width
|
||||
N_H = H // (self.stride_level * self.P_H)
|
||||
N_W = W // (self.stride_level * self.P_W)
|
||||
|
||||
# Hook decoder onto 4 layers from specified ViT layers
|
||||
layers = [encoder_tokens[hook] for hook in self.hooks]
|
||||
|
||||
# Extract only task-relevant tokens and ignore global tokens.
|
||||
layers = [self.adapt_tokens(l) for l in layers]
|
||||
|
||||
# Reshape tokens to spatial representation
|
||||
layers = [rearrange(l, 'b (nh nw) c -> b c nh nw', nh=N_H, nw=N_W) for l in layers]
|
||||
|
||||
layers = [self.act_postprocess[idx](l) for idx, l in enumerate(layers)]
|
||||
# Project layers to chosen feature dim
|
||||
layers = [self.scratch.layer_rn[idx](l) for idx, l in enumerate(layers)]
|
||||
|
||||
# Fuse layers using refinement stages
|
||||
path_4 = self.scratch.refinenet4(layers[3])[:, :, :layers[2].shape[2], :layers[2].shape[3]]
|
||||
path_3 = self.scratch.refinenet3(path_4, layers[2])
|
||||
path_2 = self.scratch.refinenet2(path_3, layers[1])
|
||||
path_1 = self.scratch.refinenet1(path_2, layers[0])
|
||||
|
||||
# Output head
|
||||
out = self.head(path_1)
|
||||
|
||||
return out
|
||||
|
||||
|
||||
class PixelwiseTaskWithDPT(nn.Module):
|
||||
""" DPT module for dust3r, can return 3D points + confidence for all pixels"""
|
||||
|
||||
def __init__(self, *, n_cls_token=0, hooks_idx=None, dim_tokens=None,
|
||||
output_width_ratio=1, num_channels=1, postprocess=None, depth_mode=None, conf_mode=None, **kwargs):
|
||||
super(PixelwiseTaskWithDPT, self).__init__()
|
||||
self.return_all_layers = True # backbone needs to return all layers
|
||||
self.postprocess = postprocess
|
||||
self.depth_mode = depth_mode
|
||||
self.conf_mode = conf_mode
|
||||
|
||||
assert n_cls_token == 0, "Not implemented"
|
||||
dpt_args = dict(output_width_ratio=output_width_ratio,
|
||||
num_channels=num_channels,
|
||||
**kwargs)
|
||||
if hooks_idx is not None:
|
||||
dpt_args.update(hooks=hooks_idx)
|
||||
self.dpt = DPTOutputAdapter_fix(**dpt_args)
|
||||
dpt_init_args = {} if dim_tokens is None else {'dim_tokens_enc': dim_tokens}
|
||||
self.dpt.init(**dpt_init_args)
|
||||
|
||||
def forward(self, x, img_info):
|
||||
out = self.dpt(x, image_size=(img_info[0], img_info[1]))
|
||||
if self.postprocess:
|
||||
out = self.postprocess(out, self.depth_mode, self.conf_mode)
|
||||
return out
|
||||
|
||||
|
||||
def create_dpt_head(net, has_conf=False):
|
||||
"""
|
||||
return PixelwiseTaskWithDPT for given net params
|
||||
"""
|
||||
assert net.dec_depth > 9
|
||||
l2 = net.dec_depth
|
||||
feature_dim = 256
|
||||
last_dim = feature_dim//2
|
||||
out_nchan = 3
|
||||
ed = net.enc_embed_dim
|
||||
dd = net.dec_embed_dim
|
||||
return PixelwiseTaskWithDPT(num_channels=out_nchan + has_conf,
|
||||
feature_dim=feature_dim,
|
||||
last_dim=last_dim,
|
||||
hooks_idx=[0, l2*2//4, l2*3//4, l2],
|
||||
dim_tokens=[ed, dd, dd, dd],
|
||||
postprocess=postprocess,
|
||||
depth_mode=net.depth_mode,
|
||||
conf_mode=net.conf_mode,
|
||||
head_type='regression')
|
||||
@@ -0,0 +1,41 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# linear head implementation for DUST3R
|
||||
# --------------------------------------------------------
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
from dust3r.heads.postprocess import postprocess
|
||||
|
||||
|
||||
class LinearPts3d (nn.Module):
|
||||
"""
|
||||
Linear head for dust3r
|
||||
Each token outputs: - 16x16 3D points (+ confidence)
|
||||
"""
|
||||
|
||||
def __init__(self, net, has_conf=False):
|
||||
super().__init__()
|
||||
self.patch_size = net.patch_embed.patch_size[0]
|
||||
self.depth_mode = net.depth_mode
|
||||
self.conf_mode = net.conf_mode
|
||||
self.has_conf = has_conf
|
||||
|
||||
self.proj = nn.Linear(net.dec_embed_dim, (3 + has_conf)*self.patch_size**2)
|
||||
|
||||
def setup(self, croconet):
|
||||
pass
|
||||
|
||||
def forward(self, decout, img_shape):
|
||||
H, W = img_shape
|
||||
tokens = decout[-1]
|
||||
B, S, D = tokens.shape
|
||||
|
||||
# extract 3D points
|
||||
feat = self.proj(tokens) # B,S,D
|
||||
feat = feat.transpose(-1, -2).view(B, -1, H//self.patch_size, W//self.patch_size)
|
||||
feat = F.pixel_shuffle(feat, self.patch_size) # B,3,H,W
|
||||
|
||||
# permute + norm depth
|
||||
return postprocess(feat, self.depth_mode, self.conf_mode)
|
||||
@@ -0,0 +1,58 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# post process function for all heads: extract 3D points/confidence from output
|
||||
# --------------------------------------------------------
|
||||
import torch
|
||||
|
||||
|
||||
def postprocess(out, depth_mode, conf_mode):
|
||||
"""
|
||||
extract 3D points/confidence from prediction head output
|
||||
"""
|
||||
fmap = out.permute(0, 2, 3, 1) # B,H,W,3
|
||||
res = dict(pts3d=reg_dense_depth(fmap[:, :, :, 0:3], mode=depth_mode))
|
||||
|
||||
if conf_mode is not None:
|
||||
res['conf'] = reg_dense_conf(fmap[:, :, :, 3], mode=conf_mode)
|
||||
return res
|
||||
|
||||
|
||||
def reg_dense_depth(xyz, mode):
|
||||
"""
|
||||
extract 3D points from prediction head output
|
||||
"""
|
||||
mode, vmin, vmax = mode
|
||||
|
||||
no_bounds = (vmin == -float('inf')) and (vmax == float('inf'))
|
||||
assert no_bounds
|
||||
|
||||
if mode == 'linear':
|
||||
if no_bounds:
|
||||
return xyz # [-inf, +inf]
|
||||
return xyz.clip(min=vmin, max=vmax)
|
||||
|
||||
# distance to origin
|
||||
d = xyz.norm(dim=-1, keepdim=True)
|
||||
xyz = xyz / d.clip(min=1e-8)
|
||||
|
||||
if mode == 'square':
|
||||
return xyz * d.square()
|
||||
|
||||
if mode == 'exp':
|
||||
return xyz * torch.expm1(d)
|
||||
|
||||
raise ValueError(f'bad {mode=}')
|
||||
|
||||
|
||||
def reg_dense_conf(x, mode):
|
||||
"""
|
||||
extract confidence from prediction head output
|
||||
"""
|
||||
mode, vmin, vmax = mode
|
||||
if mode == 'exp':
|
||||
return vmin + x.exp().clip(max=vmax-vmin)
|
||||
if mode == 'sigmoid':
|
||||
return (vmax - vmin) * torch.sigmoid(x) + vmin
|
||||
raise ValueError(f'bad {mode=}')
|
||||
+119
@@ -0,0 +1,119 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# utilities needed to load image pairs
|
||||
# --------------------------------------------------------
|
||||
import numpy as np
|
||||
import torch
|
||||
import itertools
|
||||
|
||||
|
||||
def make_pairs(imgs, scene_graph='complete', prefilter=None, symmetrize=True):
|
||||
pairs = []
|
||||
|
||||
if scene_graph == 'complete': # complete graph
|
||||
for i in range(len(imgs)):
|
||||
for j in range(i):
|
||||
pairs.append((imgs[i], imgs[j]))
|
||||
|
||||
elif scene_graph.startswith('swin'):
|
||||
winsize = int(scene_graph.split('-')[1]) if '-' in scene_graph else 3
|
||||
for i in range(len(imgs)):
|
||||
for j in range(winsize):
|
||||
idx = (i + j) % len(imgs) # explicit loop closure
|
||||
pairs.append((imgs[i], imgs[idx]))
|
||||
|
||||
elif scene_graph.startswith('oneref'):
|
||||
refid = int(scene_graph.split('-')[1]) if '-' in scene_graph else 0
|
||||
for j in range(len(imgs)):
|
||||
if j != refid:
|
||||
pairs.append((imgs[refid], imgs[j]))
|
||||
|
||||
elif scene_graph == 'pairs':
|
||||
assert len(imgs) % 2 == 0
|
||||
for i in range(0, len(imgs), 2):
|
||||
pairs.append((imgs[i], imgs[i+1]))
|
||||
|
||||
if symmetrize:
|
||||
pairs += [(img2, img1) for img1, img2 in pairs]
|
||||
|
||||
# now, remove edges
|
||||
if isinstance(prefilter, str) and prefilter.startswith('seq'):
|
||||
pairs = filter_pairs_seq(pairs, int(prefilter[3:]))
|
||||
|
||||
if isinstance(prefilter, str) and prefilter.startswith('cyc'):
|
||||
pairs = filter_pairs_seq(pairs, int(prefilter[3:]), cyclic=True)
|
||||
|
||||
return pairs
|
||||
|
||||
def make_pairs_fast(imgs, scene_graph='complete', prefilter=None, symmetrize=True):
|
||||
pairs = []
|
||||
|
||||
if scene_graph == 'complete': # complete graph
|
||||
pairs = list(itertools.combinations(imgs, 2))
|
||||
|
||||
elif scene_graph.startswith('swin'):
|
||||
winsize = int(scene_graph.split('-')[1]) if '-' in scene_graph else 3
|
||||
for i in range(len(imgs)):
|
||||
for j in range(winsize):
|
||||
idx = (i + j) % len(imgs) # explicit loop closure
|
||||
pairs.append((imgs[i], imgs[idx]))
|
||||
|
||||
elif scene_graph.startswith('oneref'):
|
||||
refid = int(scene_graph.split('-')[1]) if '-' in scene_graph else 0
|
||||
for j in range(len(imgs)):
|
||||
if j != refid:
|
||||
pairs.append((imgs[refid], imgs[j]))
|
||||
|
||||
elif scene_graph == 'pairs':
|
||||
assert len(imgs) % 2 == 0
|
||||
for i in range(0, len(imgs), 2):
|
||||
pairs.append((imgs[i], imgs[i+1]))
|
||||
|
||||
if symmetrize:
|
||||
pairs += [(img2, img1) for img1, img2 in pairs]
|
||||
|
||||
# now, remove edges
|
||||
if isinstance(prefilter, str) and prefilter.startswith('seq'):
|
||||
pairs = filter_pairs_seq(pairs, int(prefilter[3:]))
|
||||
|
||||
if isinstance(prefilter, str) and prefilter.startswith('cyc'):
|
||||
pairs = filter_pairs_seq(pairs, int(prefilter[3:]), cyclic=True)
|
||||
|
||||
return pairs
|
||||
|
||||
def sel(x, kept):
|
||||
if isinstance(x, dict):
|
||||
return {k: sel(v, kept) for k, v in x.items()}
|
||||
if isinstance(x, (torch.Tensor, np.ndarray)):
|
||||
return x[kept]
|
||||
if isinstance(x, (tuple, list)):
|
||||
return type(x)([x[k] for k in kept])
|
||||
|
||||
|
||||
def _filter_edges_seq(edges, seq_dis_thr, cyclic=False):
|
||||
# number of images
|
||||
n = max(max(e) for e in edges)+1
|
||||
|
||||
kept = []
|
||||
for e, (i, j) in enumerate(edges):
|
||||
dis = abs(i-j)
|
||||
if cyclic:
|
||||
dis = min(dis, abs(i+n-j), abs(i-n-j))
|
||||
if dis <= seq_dis_thr:
|
||||
kept.append(e)
|
||||
return kept
|
||||
|
||||
|
||||
def filter_pairs_seq(pairs, seq_dis_thr, cyclic=False):
|
||||
edges = [(img1['idx'], img2['idx']) for img1, img2 in pairs]
|
||||
kept = _filter_edges_seq(edges, seq_dis_thr, cyclic=cyclic)
|
||||
return [pairs[i] for i in kept]
|
||||
|
||||
|
||||
def filter_edges_seq(view1, view2, pred1, pred2, seq_dis_thr, cyclic=False):
|
||||
edges = [(int(i), int(j)) for i, j in zip(view1['idx'], view2['idx'])]
|
||||
kept = _filter_edges_seq(edges, seq_dis_thr, cyclic=cyclic)
|
||||
print(f'>> Filtering edges more than {seq_dis_thr} frames apart: kept {len(kept)}/{len(edges)} edges')
|
||||
return sel(view1, kept), sel(view2, kept), sel(pred1, kept), sel(pred2, kept)
|
||||
+165
@@ -0,0 +1,165 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# utilities needed for the inference
|
||||
# --------------------------------------------------------
|
||||
import tqdm
|
||||
import torch
|
||||
from dust3r.utils.device import to_cpu, collate_with_cat
|
||||
from dust3r.model import AsymmetricCroCo3DStereo, inf # noqa: F401, needed when loading the model
|
||||
from dust3r.utils.misc import invalid_to_nans
|
||||
from dust3r.utils.geometry import depthmap_to_pts3d, geotrf
|
||||
|
||||
|
||||
def load_model(model_path, device):
|
||||
print('... loading model from', model_path)
|
||||
ckpt = torch.load(model_path, map_location='cpu')
|
||||
args = ckpt['args'].model.replace("ManyAR_PatchEmbed", "PatchEmbedDust3R")
|
||||
if 'landscape_only' not in args:
|
||||
args = args[:-1] + ', landscape_only=False)'
|
||||
else:
|
||||
args = args.replace(" ", "").replace('landscape_only=True', 'landscape_only=False')
|
||||
assert "landscape_only=False" in args
|
||||
print(f"instantiating : {args}")
|
||||
net = eval(args)
|
||||
print(net.load_state_dict(ckpt['model'], strict=False))
|
||||
return net.to(device)
|
||||
|
||||
|
||||
def _interleave_imgs(img1, img2):
|
||||
res = {}
|
||||
for key, value1 in img1.items():
|
||||
value2 = img2[key]
|
||||
if isinstance(value1, torch.Tensor):
|
||||
value = torch.stack((value1, value2), dim=1).flatten(0, 1)
|
||||
else:
|
||||
value = [x for pair in zip(value1, value2) for x in pair]
|
||||
res[key] = value
|
||||
return res
|
||||
|
||||
|
||||
def make_batch_symmetric(batch):
|
||||
view1, view2 = batch
|
||||
view1, view2 = (_interleave_imgs(view1, view2), _interleave_imgs(view2, view1))
|
||||
return view1, view2
|
||||
|
||||
|
||||
def loss_of_one_batch(batch, model, criterion, device, symmetrize_batch=False, use_amp=False, ret=None):
|
||||
view1, view2 = batch
|
||||
for view in batch:
|
||||
for name in 'img pts3d valid_mask camera_pose camera_intrinsics F_matrix corres'.split(): # pseudo_focal
|
||||
if name not in view:
|
||||
continue
|
||||
view[name] = view[name].to(device, non_blocking=True)
|
||||
|
||||
if symmetrize_batch:
|
||||
view1, view2 = make_batch_symmetric(batch)
|
||||
|
||||
with torch.cuda.amp.autocast(enabled=bool(use_amp)):
|
||||
pred1, pred2 = model(view1, view2)
|
||||
|
||||
# loss is supposed to be symmetric
|
||||
with torch.cuda.amp.autocast(enabled=False):
|
||||
loss = criterion(view1, view2, pred1, pred2) if criterion is not None else None
|
||||
|
||||
result = dict(view1=view1, view2=view2, pred1=pred1, pred2=pred2, loss=loss)
|
||||
return result[ret] if ret else result
|
||||
|
||||
|
||||
@torch.no_grad()
|
||||
def inference(pairs, model, device, batch_size=8):
|
||||
print(f'>> Inference with model on {len(pairs)} image pairs')
|
||||
result = []
|
||||
|
||||
# first, check if all images have the same size
|
||||
multiple_shapes = not (check_if_same_size(pairs))
|
||||
if multiple_shapes: # force bs=1
|
||||
batch_size = 1
|
||||
|
||||
for i in tqdm.trange(0, len(pairs), batch_size):
|
||||
res = loss_of_one_batch(collate_with_cat(pairs[i:i+batch_size]), model, None, device)
|
||||
result.append(to_cpu(res))
|
||||
|
||||
result = collate_with_cat(result, lists=multiple_shapes)
|
||||
|
||||
torch.cuda.empty_cache()
|
||||
return result
|
||||
|
||||
|
||||
def check_if_same_size(pairs):
|
||||
shapes1 = [img1['img'].shape[-2:] for img1, img2 in pairs]
|
||||
shapes2 = [img2['img'].shape[-2:] for img1, img2 in pairs]
|
||||
return all(shapes1[0] == s for s in shapes1) and all(shapes2[0] == s for s in shapes2)
|
||||
|
||||
|
||||
def get_pred_pts3d(gt, pred, use_pose=False):
|
||||
if 'depth' in pred and 'pseudo_focal' in pred:
|
||||
try:
|
||||
pp = gt['camera_intrinsics'][..., :2, 2]
|
||||
except KeyError:
|
||||
pp = None
|
||||
pts3d = depthmap_to_pts3d(**pred, pp=pp)
|
||||
|
||||
elif 'pts3d' in pred:
|
||||
# pts3d from my camera
|
||||
pts3d = pred['pts3d']
|
||||
|
||||
elif 'pts3d_in_other_view' in pred:
|
||||
# pts3d from the other camera, already transformed
|
||||
assert use_pose is True
|
||||
return pred['pts3d_in_other_view'] # return!
|
||||
|
||||
if use_pose:
|
||||
camera_pose = pred.get('camera_pose')
|
||||
assert camera_pose is not None
|
||||
pts3d = geotrf(camera_pose, pts3d)
|
||||
|
||||
return pts3d
|
||||
|
||||
|
||||
def find_opt_scaling(gt_pts1, gt_pts2, pr_pts1, pr_pts2=None, fit_mode='weiszfeld_stop_grad', valid1=None, valid2=None):
|
||||
assert gt_pts1.ndim == pr_pts1.ndim == 4
|
||||
assert gt_pts1.shape == pr_pts1.shape
|
||||
if gt_pts2 is not None:
|
||||
assert gt_pts2.ndim == pr_pts2.ndim == 4
|
||||
assert gt_pts2.shape == pr_pts2.shape
|
||||
|
||||
# concat the pointcloud
|
||||
nan_gt_pts1 = invalid_to_nans(gt_pts1, valid1).flatten(1, 2)
|
||||
nan_gt_pts2 = invalid_to_nans(gt_pts2, valid2).flatten(1, 2) if gt_pts2 is not None else None
|
||||
|
||||
pr_pts1 = invalid_to_nans(pr_pts1, valid1).flatten(1, 2)
|
||||
pr_pts2 = invalid_to_nans(pr_pts2, valid2).flatten(1, 2) if pr_pts2 is not None else None
|
||||
|
||||
all_gt = torch.cat((nan_gt_pts1, nan_gt_pts2), dim=1) if gt_pts2 is not None else nan_gt_pts1
|
||||
all_pr = torch.cat((pr_pts1, pr_pts2), dim=1) if pr_pts2 is not None else pr_pts1
|
||||
|
||||
dot_gt_pr = (all_pr * all_gt).sum(dim=-1)
|
||||
dot_gt_gt = all_gt.square().sum(dim=-1)
|
||||
|
||||
if fit_mode.startswith('avg'):
|
||||
# scaling = (all_pr / all_gt).view(B, -1).mean(dim=1)
|
||||
scaling = dot_gt_pr.nanmean(dim=1) / dot_gt_gt.nanmean(dim=1)
|
||||
elif fit_mode.startswith('median'):
|
||||
scaling = (dot_gt_pr / dot_gt_gt).nanmedian(dim=1).values
|
||||
elif fit_mode.startswith('weiszfeld'):
|
||||
# init scaling with l2 closed form
|
||||
scaling = dot_gt_pr.nanmean(dim=1) / dot_gt_gt.nanmean(dim=1)
|
||||
# iterative re-weighted least-squares
|
||||
for iter in range(10):
|
||||
# re-weighting by inverse of distance
|
||||
dis = (all_pr - scaling.view(-1, 1, 1) * all_gt).norm(dim=-1)
|
||||
# print(dis.nanmean(-1))
|
||||
w = dis.clip_(min=1e-8).reciprocal()
|
||||
# update the scaling with the new weights
|
||||
scaling = (w * dot_gt_pr).nanmean(dim=1) / (w * dot_gt_gt).nanmean(dim=1)
|
||||
else:
|
||||
raise ValueError(f'bad {fit_mode=}')
|
||||
|
||||
if fit_mode.endswith('stop_grad'):
|
||||
scaling = scaling.detach()
|
||||
|
||||
scaling = scaling.clip(min=1e-3)
|
||||
# assert scaling.isfinite().all(), bb()
|
||||
return scaling
|
||||
+297
@@ -0,0 +1,297 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# Implementation of DUSt3R training losses
|
||||
# --------------------------------------------------------
|
||||
from copy import copy, deepcopy
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
|
||||
from dust3r.inference import get_pred_pts3d, find_opt_scaling
|
||||
from dust3r.utils.geometry import inv, geotrf, normalize_pointcloud
|
||||
from dust3r.utils.geometry import get_joint_pointcloud_depth, get_joint_pointcloud_center_scale
|
||||
|
||||
|
||||
def Sum(*losses_and_masks):
|
||||
loss, mask = losses_and_masks[0]
|
||||
if loss.ndim > 0:
|
||||
# we are actually returning the loss for every pixels
|
||||
return losses_and_masks
|
||||
else:
|
||||
# we are returning the global loss
|
||||
for loss2, mask2 in losses_and_masks[1:]:
|
||||
loss = loss + loss2
|
||||
return loss
|
||||
|
||||
|
||||
class LLoss (nn.Module):
|
||||
""" L-norm loss
|
||||
"""
|
||||
|
||||
def __init__(self, reduction='mean'):
|
||||
super().__init__()
|
||||
self.reduction = reduction
|
||||
|
||||
def forward(self, a, b):
|
||||
assert a.shape == b.shape and a.ndim >= 2 and 1 <= a.shape[-1] <= 3, f'Bad shape = {a.shape}'
|
||||
dist = self.distance(a, b)
|
||||
assert dist.ndim == a.ndim-1 # one dimension less
|
||||
if self.reduction == 'none':
|
||||
return dist
|
||||
if self.reduction == 'sum':
|
||||
return dist.sum()
|
||||
if self.reduction == 'mean':
|
||||
return dist.mean() if dist.numel() > 0 else dist.new_zeros(())
|
||||
raise ValueError(f'bad {self.reduction=} mode')
|
||||
|
||||
def distance(self, a, b):
|
||||
raise NotImplementedError()
|
||||
|
||||
|
||||
class L21Loss (LLoss):
|
||||
""" Euclidean distance between 3d points """
|
||||
|
||||
def distance(self, a, b):
|
||||
return torch.norm(a - b, dim=-1) # normalized L2 distance
|
||||
|
||||
|
||||
L21 = L21Loss()
|
||||
|
||||
|
||||
class Criterion (nn.Module):
|
||||
def __init__(self, criterion=None):
|
||||
super().__init__()
|
||||
assert isinstance(criterion, LLoss), f'{criterion} is not a proper criterion!'+bb()
|
||||
self.criterion = copy(criterion)
|
||||
|
||||
def get_name(self):
|
||||
return f'{type(self).__name__}({self.criterion})'
|
||||
|
||||
def with_reduction(self, mode):
|
||||
res = loss = deepcopy(self)
|
||||
while loss is not None:
|
||||
assert isinstance(loss, Criterion)
|
||||
loss.criterion.reduction = 'none' # make it return the loss for each sample
|
||||
loss = loss._loss2 # we assume loss is a Multiloss
|
||||
return res
|
||||
|
||||
|
||||
class MultiLoss (nn.Module):
|
||||
""" Easily combinable losses (also keep track of individual loss values):
|
||||
loss = MyLoss1() + 0.1*MyLoss2()
|
||||
Usage:
|
||||
Inherit from this class and override get_name() and compute_loss()
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self._alpha = 1
|
||||
self._loss2 = None
|
||||
|
||||
def compute_loss(self, *args, **kwargs):
|
||||
raise NotImplementedError()
|
||||
|
||||
def get_name(self):
|
||||
raise NotImplementedError()
|
||||
|
||||
def __mul__(self, alpha):
|
||||
assert isinstance(alpha, (int, float))
|
||||
res = copy(self)
|
||||
res._alpha = alpha
|
||||
return res
|
||||
__rmul__ = __mul__ # same
|
||||
|
||||
def __add__(self, loss2):
|
||||
assert isinstance(loss2, MultiLoss)
|
||||
res = cur = copy(self)
|
||||
# find the end of the chain
|
||||
while cur._loss2 is not None:
|
||||
cur = cur._loss2
|
||||
cur._loss2 = loss2
|
||||
return res
|
||||
|
||||
def __repr__(self):
|
||||
name = self.get_name()
|
||||
if self._alpha != 1:
|
||||
name = f'{self._alpha:g}*{name}'
|
||||
if self._loss2:
|
||||
name = f'{name} + {self._loss2}'
|
||||
return name
|
||||
|
||||
def forward(self, *args, **kwargs):
|
||||
loss = self.compute_loss(*args, **kwargs)
|
||||
if isinstance(loss, tuple):
|
||||
loss, details = loss
|
||||
elif loss.ndim == 0:
|
||||
details = {self.get_name(): float(loss)}
|
||||
else:
|
||||
details = {}
|
||||
loss = loss * self._alpha
|
||||
|
||||
if self._loss2:
|
||||
loss2, details2 = self._loss2(*args, **kwargs)
|
||||
loss = loss + loss2
|
||||
details |= details2
|
||||
|
||||
return loss, details
|
||||
|
||||
|
||||
class Regr3D (Criterion, MultiLoss):
|
||||
""" Ensure that all 3D points are correct.
|
||||
Asymmetric loss: view1 is supposed to be the anchor.
|
||||
|
||||
P1 = RT1 @ D1
|
||||
P2 = RT2 @ D2
|
||||
loss1 = (I @ pred_D1) - (RT1^-1 @ RT1 @ D1)
|
||||
loss2 = (RT21 @ pred_D2) - (RT1^-1 @ P2)
|
||||
= (RT21 @ pred_D2) - (RT1^-1 @ RT2 @ D2)
|
||||
"""
|
||||
|
||||
def __init__(self, criterion, norm_mode='avg_dis', gt_scale=False):
|
||||
super().__init__(criterion)
|
||||
self.norm_mode = norm_mode
|
||||
self.gt_scale = gt_scale
|
||||
|
||||
def get_all_pts3d(self, gt1, gt2, pred1, pred2, dist_clip=None):
|
||||
# everything is normalized w.r.t. camera of view1
|
||||
in_camera1 = inv(gt1['camera_pose'])
|
||||
gt_pts1 = geotrf(in_camera1, gt1['pts3d']) # B,H,W,3
|
||||
gt_pts2 = geotrf(in_camera1, gt2['pts3d']) # B,H,W,3
|
||||
|
||||
valid1 = gt1['valid_mask'].clone()
|
||||
valid2 = gt2['valid_mask'].clone()
|
||||
|
||||
if dist_clip is not None:
|
||||
# points that are too far-away == invalid
|
||||
dis1 = gt_pts1.norm(dim=-1) # (B, H, W)
|
||||
dis2 = gt_pts2.norm(dim=-1) # (B, H, W)
|
||||
valid1 = valid1 & (dis1 <= dist_clip)
|
||||
valid2 = valid2 & (dis2 <= dist_clip)
|
||||
|
||||
pr_pts1 = get_pred_pts3d(gt1, pred1, use_pose=False)
|
||||
pr_pts2 = get_pred_pts3d(gt2, pred2, use_pose=True)
|
||||
|
||||
# normalize 3d points
|
||||
if self.norm_mode:
|
||||
pr_pts1, pr_pts2 = normalize_pointcloud(pr_pts1, pr_pts2, self.norm_mode, valid1, valid2)
|
||||
if self.norm_mode and not self.gt_scale:
|
||||
gt_pts1, gt_pts2 = normalize_pointcloud(gt_pts1, gt_pts2, self.norm_mode, valid1, valid2)
|
||||
|
||||
return gt_pts1, gt_pts2, pr_pts1, pr_pts2, valid1, valid2, {}
|
||||
|
||||
def compute_loss(self, gt1, gt2, pred1, pred2, **kw):
|
||||
gt_pts1, gt_pts2, pred_pts1, pred_pts2, mask1, mask2, monitoring = \
|
||||
self.get_all_pts3d(gt1, gt2, pred1, pred2, **kw)
|
||||
# loss on img1 side
|
||||
l1 = self.criterion(pred_pts1[mask1], gt_pts1[mask1])
|
||||
# loss on gt2 side
|
||||
l2 = self.criterion(pred_pts2[mask2], gt_pts2[mask2])
|
||||
self_name = type(self).__name__
|
||||
details = {self_name+'_pts3d_1': float(l1.mean()), self_name+'_pts3d_2': float(l2.mean())}
|
||||
return Sum((l1, mask1), (l2, mask2)), (details | monitoring)
|
||||
|
||||
|
||||
class ConfLoss (MultiLoss):
|
||||
""" Weighted regression by learned confidence.
|
||||
Assuming the input pixel_loss is a pixel-level regression loss.
|
||||
|
||||
Principle:
|
||||
high-confidence means high conf = 0.1 ==> conf_loss = x / 10 + alpha*log(10)
|
||||
low confidence means low conf = 10 ==> conf_loss = x * 10 - alpha*log(10)
|
||||
|
||||
alpha: hyperparameter
|
||||
"""
|
||||
|
||||
def __init__(self, pixel_loss, alpha=1):
|
||||
super().__init__()
|
||||
assert alpha > 0
|
||||
self.alpha = alpha
|
||||
self.pixel_loss = pixel_loss.with_reduction('none')
|
||||
|
||||
def get_name(self):
|
||||
return f'ConfLoss({self.pixel_loss})'
|
||||
|
||||
def get_conf_log(self, x):
|
||||
return x, torch.log(x)
|
||||
|
||||
def compute_loss(self, gt1, gt2, pred1, pred2, **kw):
|
||||
# compute per-pixel loss
|
||||
((loss1, msk1), (loss2, msk2)), details = self.pixel_loss(gt1, gt2, pred1, pred2, **kw)
|
||||
if loss1.numel() == 0:
|
||||
print('NO VALID POINTS in img1', force=True)
|
||||
if loss2.numel() == 0:
|
||||
print('NO VALID POINTS in img2', force=True)
|
||||
|
||||
# weight by confidence
|
||||
conf1, log_conf1 = self.get_conf_log(pred1['conf'][msk1])
|
||||
conf2, log_conf2 = self.get_conf_log(pred2['conf'][msk2])
|
||||
conf_loss1 = loss1 * conf1 - self.alpha * log_conf1
|
||||
conf_loss2 = loss2 * conf2 - self.alpha * log_conf2
|
||||
|
||||
# average + nan protection (in case of no valid pixels at all)
|
||||
conf_loss1 = conf_loss1.mean() if conf_loss1.numel() > 0 else 0
|
||||
conf_loss2 = conf_loss2.mean() if conf_loss2.numel() > 0 else 0
|
||||
|
||||
return conf_loss1 + conf_loss2, dict(conf_loss_1=float(conf_loss1), conf_loss2=float(conf_loss2), **details)
|
||||
|
||||
|
||||
class Regr3D_ShiftInv (Regr3D):
|
||||
""" Same than Regr3D but invariant to depth shift.
|
||||
"""
|
||||
|
||||
def get_all_pts3d(self, gt1, gt2, pred1, pred2):
|
||||
# compute unnormalized points
|
||||
gt_pts1, gt_pts2, pred_pts1, pred_pts2, mask1, mask2, monitoring = \
|
||||
super().get_all_pts3d(gt1, gt2, pred1, pred2)
|
||||
|
||||
# compute median depth
|
||||
gt_z1, gt_z2 = gt_pts1[..., 2], gt_pts2[..., 2]
|
||||
pred_z1, pred_z2 = pred_pts1[..., 2], pred_pts2[..., 2]
|
||||
gt_shift_z = get_joint_pointcloud_depth(gt_z1, gt_z2, mask1, mask2)[:, None, None]
|
||||
pred_shift_z = get_joint_pointcloud_depth(pred_z1, pred_z2, mask1, mask2)[:, None, None]
|
||||
|
||||
# subtract the median depth
|
||||
gt_z1 -= gt_shift_z
|
||||
gt_z2 -= gt_shift_z
|
||||
pred_z1 -= pred_shift_z
|
||||
pred_z2 -= pred_shift_z
|
||||
|
||||
# monitoring = dict(monitoring, gt_shift_z=gt_shift_z.mean().detach(), pred_shift_z=pred_shift_z.mean().detach())
|
||||
return gt_pts1, gt_pts2, pred_pts1, pred_pts2, mask1, mask2, monitoring
|
||||
|
||||
|
||||
class Regr3D_ScaleInv (Regr3D):
|
||||
""" Same than Regr3D but invariant to depth shift.
|
||||
if gt_scale == True: enforce the prediction to take the same scale than GT
|
||||
"""
|
||||
|
||||
def get_all_pts3d(self, gt1, gt2, pred1, pred2):
|
||||
# compute depth-normalized points
|
||||
gt_pts1, gt_pts2, pred_pts1, pred_pts2, mask1, mask2, monitoring = super().get_all_pts3d(gt1, gt2, pred1, pred2)
|
||||
|
||||
# measure scene scale
|
||||
_, gt_scale = get_joint_pointcloud_center_scale(gt_pts1, gt_pts2, mask1, mask2)
|
||||
_, pred_scale = get_joint_pointcloud_center_scale(pred_pts1, pred_pts2, mask1, mask2)
|
||||
|
||||
# prevent predictions to be in a ridiculous range
|
||||
pred_scale = pred_scale.clip(min=1e-3, max=1e3)
|
||||
|
||||
# subtract the median depth
|
||||
if self.gt_scale:
|
||||
pred_pts1 *= gt_scale / pred_scale
|
||||
pred_pts2 *= gt_scale / pred_scale
|
||||
# monitoring = dict(monitoring, pred_scale=(pred_scale/gt_scale).mean())
|
||||
else:
|
||||
gt_pts1 /= gt_scale
|
||||
gt_pts2 /= gt_scale
|
||||
pred_pts1 /= pred_scale
|
||||
pred_pts2 /= pred_scale
|
||||
# monitoring = dict(monitoring, gt_scale=gt_scale.mean(), pred_scale=pred_scale.mean().detach())
|
||||
|
||||
return gt_pts1, gt_pts2, pred_pts1, pred_pts2, mask1, mask2, monitoring
|
||||
|
||||
|
||||
class Regr3D_ScaleShiftInv (Regr3D_ScaleInv, Regr3D_ShiftInv):
|
||||
# calls Regr3D_ShiftInv first, then Regr3D_ScaleInv
|
||||
pass
|
||||
+166
@@ -0,0 +1,166 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# DUSt3R model class
|
||||
# --------------------------------------------------------
|
||||
from copy import deepcopy
|
||||
import torch
|
||||
|
||||
from .utils.misc import fill_default_args, freeze_all_params, is_symmetrized, interleave, transpose_to_landscape
|
||||
from .heads import head_factory
|
||||
from dust3r.patch_embed import get_patch_embed
|
||||
|
||||
import dust3r.utils.path_to_croco # noqa: F401
|
||||
from models.croco import CroCoNet # noqa
|
||||
inf = float('inf')
|
||||
|
||||
|
||||
class AsymmetricCroCo3DStereo (CroCoNet):
|
||||
""" Two siamese encoders, followed by two decoders.
|
||||
The goal is to output 3d points directly, both images in view1's frame
|
||||
(hence the asymmetry).
|
||||
"""
|
||||
|
||||
def __init__(self,
|
||||
output_mode='pts3d',
|
||||
head_type='linear',
|
||||
depth_mode=('exp', -inf, inf),
|
||||
conf_mode=('exp', 1, inf),
|
||||
freeze='none',
|
||||
landscape_only=True,
|
||||
patch_embed_cls='PatchEmbedDust3R', # PatchEmbedDust3R or ManyAR_PatchEmbed
|
||||
**croco_kwargs):
|
||||
self.patch_embed_cls = patch_embed_cls
|
||||
self.croco_args = fill_default_args(croco_kwargs, super().__init__)
|
||||
super().__init__(**croco_kwargs)
|
||||
|
||||
# dust3r specific initialization
|
||||
self.dec_blocks2 = deepcopy(self.dec_blocks)
|
||||
self.set_downstream_head(output_mode, head_type, landscape_only, depth_mode, conf_mode, **croco_kwargs)
|
||||
self.set_freeze(freeze)
|
||||
|
||||
def _set_patch_embed(self, img_size=224, patch_size=16, enc_embed_dim=768):
|
||||
self.patch_embed = get_patch_embed(self.patch_embed_cls, img_size, patch_size, enc_embed_dim)
|
||||
|
||||
def load_state_dict(self, ckpt, **kw):
|
||||
# duplicate all weights for the second decoder if not present
|
||||
new_ckpt = dict(ckpt)
|
||||
if not any(k.startswith('dec_blocks2') for k in ckpt):
|
||||
for key, value in ckpt.items():
|
||||
if key.startswith('dec_blocks'):
|
||||
new_ckpt[key.replace('dec_blocks', 'dec_blocks2')] = value
|
||||
return super().load_state_dict(new_ckpt, **kw)
|
||||
|
||||
def set_freeze(self, freeze): # this is for use by downstream models
|
||||
self.freeze = freeze
|
||||
to_be_frozen = {
|
||||
'none': [],
|
||||
'mask': [self.mask_token],
|
||||
'encoder': [self.mask_token, self.patch_embed, self.enc_blocks],
|
||||
}
|
||||
freeze_all_params(to_be_frozen[freeze])
|
||||
|
||||
def _set_prediction_head(self, *args, **kwargs):
|
||||
""" No prediction head """
|
||||
return
|
||||
|
||||
def set_downstream_head(self, output_mode, head_type, landscape_only, depth_mode, conf_mode, patch_size, img_size,
|
||||
**kw):
|
||||
assert img_size[0] % patch_size == 0 and img_size[1] % patch_size == 0, \
|
||||
f'{img_size=} must be multiple of {patch_size=}'
|
||||
self.output_mode = output_mode
|
||||
self.head_type = head_type
|
||||
self.depth_mode = depth_mode
|
||||
self.conf_mode = conf_mode
|
||||
# allocate heads
|
||||
self.downstream_head1 = head_factory(head_type, output_mode, self, has_conf=bool(conf_mode))
|
||||
self.downstream_head2 = head_factory(head_type, output_mode, self, has_conf=bool(conf_mode))
|
||||
# magic wrapper
|
||||
self.head1 = transpose_to_landscape(self.downstream_head1, activate=landscape_only)
|
||||
self.head2 = transpose_to_landscape(self.downstream_head2, activate=landscape_only)
|
||||
|
||||
def _encode_image(self, image, true_shape):
|
||||
# embed the image into patches (x has size B x Npatches x C)
|
||||
x, pos = self.patch_embed(image, true_shape=true_shape)
|
||||
|
||||
# add positional embedding without cls token
|
||||
assert self.enc_pos_embed is None
|
||||
|
||||
# now apply the transformer encoder and normalization
|
||||
for blk in self.enc_blocks:
|
||||
x = blk(x, pos)
|
||||
|
||||
x = self.enc_norm(x)
|
||||
return x, pos, None
|
||||
|
||||
def _encode_image_pairs(self, img1, img2, true_shape1, true_shape2):
|
||||
if img1.shape[-2:] == img2.shape[-2:]:
|
||||
out, pos, _ = self._encode_image(torch.cat((img1, img2), dim=0),
|
||||
torch.cat((true_shape1, true_shape2), dim=0))
|
||||
out, out2 = out.chunk(2, dim=0)
|
||||
pos, pos2 = pos.chunk(2, dim=0)
|
||||
else:
|
||||
out, pos, _ = self._encode_image(img1, true_shape1)
|
||||
out2, pos2, _ = self._encode_image(img2, true_shape2)
|
||||
return out, out2, pos, pos2
|
||||
|
||||
def _encode_symmetrized(self, view1, view2):
|
||||
img1 = view1['img']
|
||||
img2 = view2['img']
|
||||
B = img1.shape[0]
|
||||
# Recover true_shape when available, otherwise assume that the img shape is the true one
|
||||
shape1 = view1.get('true_shape', torch.tensor(img1.shape[-2:])[None].repeat(B, 1))
|
||||
shape2 = view2.get('true_shape', torch.tensor(img2.shape[-2:])[None].repeat(B, 1))
|
||||
# warning! maybe the images have different portrait/landscape orientations
|
||||
|
||||
if is_symmetrized(view1, view2):
|
||||
# computing half of forward pass!'
|
||||
feat1, feat2, pos1, pos2 = self._encode_image_pairs(img1[::2], img2[::2], shape1[::2], shape2[::2])
|
||||
feat1, feat2 = interleave(feat1, feat2)
|
||||
pos1, pos2 = interleave(pos1, pos2)
|
||||
else:
|
||||
feat1, feat2, pos1, pos2 = self._encode_image_pairs(img1, img2, shape1, shape2)
|
||||
|
||||
return (shape1, shape2), (feat1, feat2), (pos1, pos2)
|
||||
|
||||
def _decoder(self, f1, pos1, f2, pos2):
|
||||
final_output = [(f1, f2)] # before projection
|
||||
|
||||
# project to decoder dim
|
||||
f1 = self.decoder_embed(f1)
|
||||
f2 = self.decoder_embed(f2)
|
||||
|
||||
final_output.append((f1, f2))
|
||||
for blk1, blk2 in zip(self.dec_blocks, self.dec_blocks2):
|
||||
# img1 side
|
||||
f1, _ = blk1(*final_output[-1][::+1], pos1, pos2)
|
||||
# img2 side
|
||||
f2, _ = blk2(*final_output[-1][::-1], pos2, pos1)
|
||||
# store the result
|
||||
final_output.append((f1, f2))
|
||||
|
||||
# normalize last output
|
||||
del final_output[1] # duplicate with final_output[0]
|
||||
final_output[-1] = tuple(map(self.dec_norm, final_output[-1]))
|
||||
return zip(*final_output)
|
||||
|
||||
def _downstream_head(self, head_num, decout, img_shape):
|
||||
B, S, D = decout[-1].shape
|
||||
# img_shape = tuple(map(int, img_shape))
|
||||
head = getattr(self, f'head{head_num}')
|
||||
return head(decout, img_shape)
|
||||
|
||||
def forward(self, view1, view2):
|
||||
# encode the two images --> B,S,D
|
||||
(shape1, shape2), (feat1, feat2), (pos1, pos2) = self._encode_symmetrized(view1, view2)
|
||||
|
||||
# combine all ref images into object-centric representation
|
||||
dec1, dec2 = self._decoder(feat1, pos1, feat2, pos2)
|
||||
|
||||
with torch.cuda.amp.autocast(enabled=False):
|
||||
res1 = self._downstream_head(1, [tok.float() for tok in dec1], shape1)
|
||||
res2 = self._downstream_head(2, [tok.float() for tok in dec2], shape2)
|
||||
|
||||
res2['pts3d_in_other_view'] = res2.pop('pts3d') # predict view2's pts3d in view1's frame
|
||||
return res1, res2
|
||||
@@ -0,0 +1,14 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# optimization functions
|
||||
# --------------------------------------------------------
|
||||
|
||||
|
||||
def adjust_learning_rate_by_lr(optimizer, lr):
|
||||
for param_group in optimizer.param_groups:
|
||||
if "lr_scale" in param_group:
|
||||
param_group["lr"] = lr * param_group["lr_scale"]
|
||||
else:
|
||||
param_group["lr"] = lr
|
||||
+70
@@ -0,0 +1,70 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# PatchEmbed implementation for DUST3R,
|
||||
# in particular ManyAR_PatchEmbed that Handle images with non-square aspect ratio
|
||||
# --------------------------------------------------------
|
||||
import torch
|
||||
import dust3r.utils.path_to_croco # noqa: F401
|
||||
from models.blocks import PatchEmbed # noqa
|
||||
|
||||
|
||||
def get_patch_embed(patch_embed_cls, img_size, patch_size, enc_embed_dim):
|
||||
assert patch_embed_cls in ['PatchEmbedDust3R', 'ManyAR_PatchEmbed']
|
||||
patch_embed = eval(patch_embed_cls)(img_size, patch_size, 3, enc_embed_dim)
|
||||
return patch_embed
|
||||
|
||||
|
||||
class PatchEmbedDust3R(PatchEmbed):
|
||||
def forward(self, x, **kw):
|
||||
B, C, H, W = x.shape
|
||||
assert H % self.patch_size[0] == 0, f"Input image height ({H}) is not a multiple of patch size ({self.patch_size[0]})."
|
||||
assert W % self.patch_size[1] == 0, f"Input image width ({W}) is not a multiple of patch size ({self.patch_size[1]})."
|
||||
x = self.proj(x)
|
||||
pos = self.position_getter(B, x.size(2), x.size(3), x.device)
|
||||
if self.flatten:
|
||||
x = x.flatten(2).transpose(1, 2) # BCHW -> BNC
|
||||
x = self.norm(x)
|
||||
return x, pos
|
||||
|
||||
|
||||
class ManyAR_PatchEmbed (PatchEmbed):
|
||||
""" Handle images with non-square aspect ratio.
|
||||
All images in the same batch have the same aspect ratio.
|
||||
true_shape = [(height, width) ...] indicates the actual shape of each image.
|
||||
"""
|
||||
|
||||
def __init__(self, img_size=224, patch_size=16, in_chans=3, embed_dim=768, norm_layer=None, flatten=True):
|
||||
self.embed_dim = embed_dim
|
||||
super().__init__(img_size, patch_size, in_chans, embed_dim, norm_layer, flatten)
|
||||
|
||||
def forward(self, img, true_shape):
|
||||
B, C, H, W = img.shape
|
||||
assert W >= H, f'img should be in landscape mode, but got {W=} {H=}'
|
||||
assert H % self.patch_size[0] == 0, f"Input image height ({H}) is not a multiple of patch size ({self.patch_size[0]})."
|
||||
assert W % self.patch_size[1] == 0, f"Input image width ({W}) is not a multiple of patch size ({self.patch_size[1]})."
|
||||
assert true_shape.shape == (B, 2), f"true_shape has the wrong shape={true_shape.shape}"
|
||||
|
||||
# size expressed in tokens
|
||||
W //= self.patch_size[0]
|
||||
H //= self.patch_size[1]
|
||||
n_tokens = H * W
|
||||
|
||||
height, width = true_shape.T
|
||||
is_landscape = (width >= height)
|
||||
is_portrait = ~is_landscape
|
||||
|
||||
# allocate result
|
||||
x = img.new_zeros((B, n_tokens, self.embed_dim))
|
||||
pos = img.new_zeros((B, n_tokens, 2), dtype=torch.int64)
|
||||
|
||||
# linear projection, transposed if necessary
|
||||
x[is_landscape] = self.proj(img[is_landscape]).permute(0, 2, 3, 1).flatten(1, 2).float()
|
||||
x[is_portrait] = self.proj(img[is_portrait].swapaxes(-1, -2)).permute(0, 2, 3, 1).flatten(1, 2).float()
|
||||
|
||||
pos[is_landscape] = self.position_getter(1, H, W, pos.device)
|
||||
pos[is_portrait] = self.position_getter(1, W, H, pos.device)
|
||||
|
||||
x = self.norm(x)
|
||||
return x, pos
|
||||
@@ -0,0 +1,60 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# utilities for interpreting the DUST3R output
|
||||
# --------------------------------------------------------
|
||||
import numpy as np
|
||||
import torch
|
||||
from dust3r.utils.geometry import xy_grid
|
||||
|
||||
|
||||
def estimate_focal_knowing_depth(pts3d, pp, focal_mode='median', min_focal=0.5, max_focal=3.5):
|
||||
""" Reprojection method, for when the absolute depth is known:
|
||||
1) estimate the camera focal using a robust estimator
|
||||
2) reproject points onto true rays, minimizing a certain error
|
||||
"""
|
||||
B, H, W, THREE = pts3d.shape
|
||||
assert THREE == 3
|
||||
|
||||
# centered pixel grid
|
||||
pixels = xy_grid(W, H, device=pts3d.device).view(1, -1, 2) - pp.view(-1, 1, 2) # B,HW,2
|
||||
pts3d = pts3d.flatten(1, 2) # (B, HW, 3)
|
||||
|
||||
if focal_mode == 'median':
|
||||
with torch.no_grad():
|
||||
# direct estimation of focal
|
||||
u, v = pixels.unbind(dim=-1)
|
||||
x, y, z = pts3d.unbind(dim=-1)
|
||||
fx_votes = (u * z) / x
|
||||
fy_votes = (v * z) / y
|
||||
|
||||
# assume square pixels, hence same focal for X and Y
|
||||
f_votes = torch.cat((fx_votes.view(B, -1), fy_votes.view(B, -1)), dim=-1)
|
||||
focal = torch.nanmedian(f_votes, dim=-1).values
|
||||
|
||||
elif focal_mode == 'weiszfeld':
|
||||
# init focal with l2 closed form
|
||||
# we try to find focal = argmin Sum | pixel - focal * (x,y)/z|
|
||||
xy_over_z = (pts3d[..., :2] / pts3d[..., 2:3]).nan_to_num(posinf=0, neginf=0) # homogeneous (x,y,1)
|
||||
|
||||
dot_xy_px = (xy_over_z * pixels).sum(dim=-1)
|
||||
dot_xy_xy = xy_over_z.square().sum(dim=-1)
|
||||
|
||||
focal = dot_xy_px.mean(dim=1) / dot_xy_xy.mean(dim=1)
|
||||
|
||||
# iterative re-weighted least-squares
|
||||
for iter in range(10):
|
||||
# re-weighting by inverse of distance
|
||||
dis = (pixels - focal.view(-1, 1, 1) * xy_over_z).norm(dim=-1)
|
||||
# print(dis.nanmean(-1))
|
||||
w = dis.clip(min=1e-8).reciprocal()
|
||||
# update the scaling with the new weights
|
||||
focal = (w * dot_xy_px).mean(dim=1) / (w * dot_xy_xy).mean(dim=1)
|
||||
else:
|
||||
raise ValueError(f'bad {focal_mode=}')
|
||||
|
||||
focal_base = max(H, W) / (2 * np.tan(np.deg2rad(60) / 2)) # size / 1.1547005383792515
|
||||
focal = focal.clip(min=min_focal*focal_base, max=max_focal*focal_base)
|
||||
# print(focal)
|
||||
return focal
|
||||
@@ -0,0 +1,2 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
@@ -0,0 +1,76 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# utilitary functions for DUSt3R
|
||||
# --------------------------------------------------------
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
|
||||
def todevice(batch, device, callback=None, non_blocking=False):
|
||||
''' Transfer some variables to another device (i.e. GPU, CPU:torch, CPU:numpy).
|
||||
|
||||
batch: list, tuple, dict of tensors or other things
|
||||
device: pytorch device or 'numpy'
|
||||
callback: function that would be called on every sub-elements.
|
||||
'''
|
||||
if callback:
|
||||
batch = callback(batch)
|
||||
|
||||
if isinstance(batch, dict):
|
||||
return {k: todevice(v, device) for k, v in batch.items()}
|
||||
|
||||
if isinstance(batch, (tuple, list)):
|
||||
return type(batch)(todevice(x, device) for x in batch)
|
||||
|
||||
x = batch
|
||||
if device == 'numpy':
|
||||
if isinstance(x, torch.Tensor):
|
||||
x = x.detach().cpu().numpy()
|
||||
elif x is not None:
|
||||
if isinstance(x, np.ndarray):
|
||||
x = torch.from_numpy(x)
|
||||
if torch.is_tensor(x):
|
||||
x = x.to(device, non_blocking=non_blocking)
|
||||
return x
|
||||
|
||||
|
||||
to_device = todevice # alias
|
||||
|
||||
|
||||
def to_numpy(x): return todevice(x, 'numpy')
|
||||
def to_cpu(x): return todevice(x, 'cpu')
|
||||
def to_cuda(x): return todevice(x, 'cuda')
|
||||
|
||||
|
||||
def collate_with_cat(whatever, lists=False):
|
||||
if isinstance(whatever, dict):
|
||||
return {k: collate_with_cat(vals, lists=lists) for k, vals in whatever.items()}
|
||||
|
||||
elif isinstance(whatever, (tuple, list)):
|
||||
if len(whatever) == 0:
|
||||
return whatever
|
||||
elem = whatever[0]
|
||||
T = type(whatever)
|
||||
|
||||
if elem is None:
|
||||
return None
|
||||
if isinstance(elem, (bool, float, int, str)):
|
||||
return whatever
|
||||
if isinstance(elem, tuple):
|
||||
return T(collate_with_cat(x, lists=lists) for x in zip(*whatever))
|
||||
if isinstance(elem, dict):
|
||||
return {k: collate_with_cat([e[k] for e in whatever], lists=lists) for k in elem}
|
||||
|
||||
if isinstance(elem, torch.Tensor):
|
||||
return listify(whatever) if lists else torch.cat(whatever)
|
||||
if isinstance(elem, np.ndarray):
|
||||
return listify(whatever) if lists else torch.cat([torch.from_numpy(x) for x in whatever])
|
||||
|
||||
# otherwise, we just chain lists
|
||||
return sum(whatever, T())
|
||||
|
||||
|
||||
def listify(elems):
|
||||
return [x for e in elems for x in e]
|
||||
+361
@@ -0,0 +1,361 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# geometry utilitary functions
|
||||
# --------------------------------------------------------
|
||||
import torch
|
||||
import numpy as np
|
||||
from scipy.spatial import cKDTree as KDTree
|
||||
|
||||
from dust3r.utils.misc import invalid_to_zeros, invalid_to_nans
|
||||
from dust3r.utils.device import to_numpy
|
||||
|
||||
|
||||
def xy_grid(W, H, device=None, origin=(0, 0), unsqueeze=None, cat_dim=-1, homogeneous=False, **arange_kw):
|
||||
""" Output a (H,W,2) array of int32
|
||||
with output[j,i,0] = i + origin[0]
|
||||
output[j,i,1] = j + origin[1]
|
||||
"""
|
||||
if device is None:
|
||||
# numpy
|
||||
arange, meshgrid, stack, ones = np.arange, np.meshgrid, np.stack, np.ones
|
||||
else:
|
||||
# torch
|
||||
arange = lambda *a, **kw: torch.arange(*a, device=device, **kw)
|
||||
meshgrid, stack = torch.meshgrid, torch.stack
|
||||
ones = lambda *a: torch.ones(*a, device=device)
|
||||
|
||||
tw, th = [arange(o, o+s, **arange_kw) for s, o in zip((W, H), origin)]
|
||||
grid = meshgrid(tw, th, indexing='xy')
|
||||
if homogeneous:
|
||||
grid = grid + (ones((H, W)),)
|
||||
if unsqueeze is not None:
|
||||
grid = (grid[0].unsqueeze(unsqueeze), grid[1].unsqueeze(unsqueeze))
|
||||
if cat_dim is not None:
|
||||
grid = stack(grid, cat_dim)
|
||||
return grid
|
||||
|
||||
|
||||
def geotrf(Trf, pts, ncol=None, norm=False):
|
||||
""" Apply a geometric transformation to a list of 3-D points.
|
||||
|
||||
H: 3x3 or 4x4 projection matrix (typically a Homography)
|
||||
p: numpy/torch/tuple of coordinates. Shape must be (...,2) or (...,3)
|
||||
|
||||
ncol: int. number of columns of the result (2 or 3)
|
||||
norm: float. if != 0, the resut is projected on the z=norm plane.
|
||||
|
||||
Returns an array of projected 2d points.
|
||||
"""
|
||||
assert Trf.ndim >= 2
|
||||
if isinstance(Trf, np.ndarray):
|
||||
pts = np.asarray(pts)
|
||||
elif isinstance(Trf, torch.Tensor):
|
||||
pts = torch.as_tensor(pts, dtype=Trf.dtype)
|
||||
|
||||
# adapt shape if necessary
|
||||
output_reshape = pts.shape[:-1]
|
||||
ncol = ncol or pts.shape[-1]
|
||||
|
||||
# optimized code
|
||||
if (isinstance(Trf, torch.Tensor) and isinstance(pts, torch.Tensor) and
|
||||
Trf.ndim == 3 and pts.ndim == 4):
|
||||
d = pts.shape[3]
|
||||
if Trf.shape[-1] == d:
|
||||
pts = torch.einsum("bij, bhwj -> bhwi", Trf, pts)
|
||||
elif Trf.shape[-1] == d+1:
|
||||
pts = torch.einsum("bij, bhwj -> bhwi", Trf[:, :d, :d], pts) + Trf[:, None, None, :d, d]
|
||||
else:
|
||||
raise ValueError(f'bad shape, not ending with 3 or 4, for {pts.shape=}')
|
||||
else:
|
||||
if Trf.ndim >= 3:
|
||||
n = Trf.ndim-2
|
||||
assert Trf.shape[:n] == pts.shape[:n], 'batch size does not match'
|
||||
Trf = Trf.reshape(-1, Trf.shape[-2], Trf.shape[-1])
|
||||
|
||||
if pts.ndim > Trf.ndim:
|
||||
# Trf == (B,d,d) & pts == (B,H,W,d) --> (B, H*W, d)
|
||||
pts = pts.reshape(Trf.shape[0], -1, pts.shape[-1])
|
||||
elif pts.ndim == 2:
|
||||
# Trf == (B,d,d) & pts == (B,d) --> (B, 1, d)
|
||||
pts = pts[:, None, :]
|
||||
|
||||
if pts.shape[-1]+1 == Trf.shape[-1]:
|
||||
Trf = Trf.swapaxes(-1, -2) # transpose Trf
|
||||
pts = pts @ Trf[..., :-1, :] + Trf[..., -1:, :]
|
||||
elif pts.shape[-1] == Trf.shape[-1]:
|
||||
Trf = Trf.swapaxes(-1, -2) # transpose Trf
|
||||
pts = pts @ Trf
|
||||
else:
|
||||
pts = Trf @ pts.T
|
||||
if pts.ndim >= 2:
|
||||
pts = pts.swapaxes(-1, -2)
|
||||
|
||||
if norm:
|
||||
pts = pts / pts[..., -1:] # DONT DO /= BECAUSE OF WEIRD PYTORCH BUG
|
||||
if norm != 1:
|
||||
pts *= norm
|
||||
|
||||
res = pts[..., :ncol].reshape(*output_reshape, ncol)
|
||||
return res
|
||||
|
||||
|
||||
def inv(mat):
|
||||
""" Invert a torch or numpy matrix
|
||||
"""
|
||||
if isinstance(mat, torch.Tensor):
|
||||
return torch.linalg.inv(mat)
|
||||
if isinstance(mat, np.ndarray):
|
||||
return np.linalg.inv(mat)
|
||||
raise ValueError(f'bad matrix type = {type(mat)}')
|
||||
|
||||
|
||||
def depthmap_to_pts3d(depth, pseudo_focal, pp=None, **_):
|
||||
"""
|
||||
Args:
|
||||
- depthmap (BxHxW array):
|
||||
- pseudo_focal: [B,H,W] ; [B,2,H,W] or [B,1,H,W]
|
||||
Returns:
|
||||
pointmap of absolute coordinates (BxHxWx3 array)
|
||||
"""
|
||||
|
||||
if len(depth.shape) == 4:
|
||||
B, H, W, n = depth.shape
|
||||
else:
|
||||
B, H, W = depth.shape
|
||||
n = None
|
||||
|
||||
if len(pseudo_focal.shape) == 3: # [B,H,W]
|
||||
pseudo_focalx = pseudo_focaly = pseudo_focal
|
||||
elif len(pseudo_focal.shape) == 4: # [B,2,H,W] or [B,1,H,W]
|
||||
pseudo_focalx = pseudo_focal[:, 0]
|
||||
if pseudo_focal.shape[1] == 2:
|
||||
pseudo_focaly = pseudo_focal[:, 1]
|
||||
else:
|
||||
pseudo_focaly = pseudo_focalx
|
||||
else:
|
||||
raise NotImplementedError("Error, unknown input focal shape format.")
|
||||
|
||||
assert pseudo_focalx.shape == depth.shape[:3]
|
||||
assert pseudo_focaly.shape == depth.shape[:3]
|
||||
grid_x, grid_y = xy_grid(W, H, cat_dim=0, device=depth.device)[:, None]
|
||||
|
||||
# set principal point
|
||||
if pp is None:
|
||||
grid_x = grid_x - (W-1)/2
|
||||
grid_y = grid_y - (H-1)/2
|
||||
else:
|
||||
grid_x = grid_x.expand(B, -1, -1) - pp[:, 0, None, None]
|
||||
grid_y = grid_y.expand(B, -1, -1) - pp[:, 1, None, None]
|
||||
|
||||
if n is None:
|
||||
pts3d = torch.empty((B, H, W, 3), device=depth.device)
|
||||
pts3d[..., 0] = depth * grid_x / pseudo_focalx
|
||||
pts3d[..., 1] = depth * grid_y / pseudo_focaly
|
||||
pts3d[..., 2] = depth
|
||||
else:
|
||||
pts3d = torch.empty((B, H, W, 3, n), device=depth.device)
|
||||
pts3d[..., 0, :] = depth * (grid_x / pseudo_focalx)[..., None]
|
||||
pts3d[..., 1, :] = depth * (grid_y / pseudo_focaly)[..., None]
|
||||
pts3d[..., 2, :] = depth
|
||||
return pts3d
|
||||
|
||||
|
||||
def depthmap_to_camera_coordinates(depthmap, camera_intrinsics, pseudo_focal=None):
|
||||
"""
|
||||
Args:
|
||||
- depthmap (HxW array):
|
||||
- camera_intrinsics: a 3x3 matrix
|
||||
Returns:
|
||||
pointmap of absolute coordinates (HxWx3 array), and a mask specifying valid pixels.
|
||||
"""
|
||||
camera_intrinsics = np.float32(camera_intrinsics)
|
||||
H, W = depthmap.shape
|
||||
|
||||
# Compute 3D ray associated with each pixel
|
||||
# Strong assumption: there are no skew terms
|
||||
assert camera_intrinsics[0, 1] == 0.0
|
||||
assert camera_intrinsics[1, 0] == 0.0
|
||||
if pseudo_focal is None:
|
||||
fu = camera_intrinsics[0, 0]
|
||||
fv = camera_intrinsics[1, 1]
|
||||
else:
|
||||
assert pseudo_focal.shape == (H, W)
|
||||
fu = fv = pseudo_focal
|
||||
cu = camera_intrinsics[0, 2]
|
||||
cv = camera_intrinsics[1, 2]
|
||||
|
||||
u, v = np.meshgrid(np.arange(W), np.arange(H))
|
||||
z_cam = depthmap
|
||||
x_cam = (u - cu) * z_cam / fu
|
||||
y_cam = (v - cv) * z_cam / fv
|
||||
X_cam = np.stack((x_cam, y_cam, z_cam), axis=-1).astype(np.float32)
|
||||
|
||||
# Mask for valid coordinates
|
||||
valid_mask = (depthmap > 0.0)
|
||||
return X_cam, valid_mask
|
||||
|
||||
|
||||
def depthmap_to_absolute_camera_coordinates(depthmap, camera_intrinsics, camera_pose, **kw):
|
||||
"""
|
||||
Args:
|
||||
- depthmap (HxW array):
|
||||
- camera_intrinsics: a 3x3 matrix
|
||||
- camera_pose: a 4x3 or 4x4 cam2world matrix
|
||||
Returns:
|
||||
pointmap of absolute coordinates (HxWx3 array), and a mask specifying valid pixels."""
|
||||
X_cam, valid_mask = depthmap_to_camera_coordinates(depthmap, camera_intrinsics)
|
||||
|
||||
# R_cam2world = np.float32(camera_params["R_cam2world"])
|
||||
# t_cam2world = np.float32(camera_params["t_cam2world"]).squeeze()
|
||||
R_cam2world = camera_pose[:3, :3]
|
||||
t_cam2world = camera_pose[:3, 3]
|
||||
|
||||
# Express in absolute coordinates (invalid depth values)
|
||||
X_world = np.einsum("ik, vuk -> vui", R_cam2world, X_cam) + t_cam2world[None, None, :]
|
||||
return X_world, valid_mask
|
||||
|
||||
|
||||
def colmap_to_opencv_intrinsics(K):
|
||||
"""
|
||||
Modify camera intrinsics to follow a different convention.
|
||||
Coordinates of the center of the top-left pixels are by default:
|
||||
- (0.5, 0.5) in Colmap
|
||||
- (0,0) in OpenCV
|
||||
"""
|
||||
K = K.copy()
|
||||
K[0, 2] -= 0.5
|
||||
K[1, 2] -= 0.5
|
||||
return K
|
||||
|
||||
|
||||
def opencv_to_colmap_intrinsics(K):
|
||||
"""
|
||||
Modify camera intrinsics to follow a different convention.
|
||||
Coordinates of the center of the top-left pixels are by default:
|
||||
- (0.5, 0.5) in Colmap
|
||||
- (0,0) in OpenCV
|
||||
"""
|
||||
K = K.copy()
|
||||
K[0, 2] += 0.5
|
||||
K[1, 2] += 0.5
|
||||
return K
|
||||
|
||||
|
||||
def normalize_pointcloud(pts1, pts2, norm_mode='avg_dis', valid1=None, valid2=None):
|
||||
""" renorm pointmaps pts1, pts2 with norm_mode
|
||||
"""
|
||||
assert pts1.ndim >= 3 and pts1.shape[-1] == 3
|
||||
assert pts2 is None or (pts2.ndim >= 3 and pts2.shape[-1] == 3)
|
||||
norm_mode, dis_mode = norm_mode.split('_')
|
||||
|
||||
if norm_mode == 'avg':
|
||||
# gather all points together (joint normalization)
|
||||
nan_pts1, nnz1 = invalid_to_zeros(pts1, valid1, ndim=3)
|
||||
nan_pts2, nnz2 = invalid_to_zeros(pts2, valid2, ndim=3) if pts2 is not None else (None, 0)
|
||||
all_pts = torch.cat((nan_pts1, nan_pts2), dim=1) if pts2 is not None else nan_pts1
|
||||
|
||||
# compute distance to origin
|
||||
all_dis = all_pts.norm(dim=-1)
|
||||
if dis_mode == 'dis':
|
||||
pass # do nothing
|
||||
elif dis_mode == 'log1p':
|
||||
all_dis = torch.log1p(all_dis)
|
||||
elif dis_mode == 'warp-log1p':
|
||||
# actually warp input points before normalizing them
|
||||
log_dis = torch.log1p(all_dis)
|
||||
warp_factor = log_dis / all_dis.clip(min=1e-8)
|
||||
H1, W1 = pts1.shape[1:-1]
|
||||
pts1 = pts1 * warp_factor[:, :W1*H1].view(-1, H1, W1, 1)
|
||||
if pts2 is not None:
|
||||
H2, W2 = pts2.shape[1:-1]
|
||||
pts2 = pts2 * warp_factor[:, W1*H1:].view(-1, H2, W2, 1)
|
||||
all_dis = log_dis # this is their true distance afterwards
|
||||
else:
|
||||
raise ValueError(f'bad {dis_mode=}')
|
||||
|
||||
norm_factor = all_dis.sum(dim=1) / (nnz1 + nnz2 + 1e-8)
|
||||
else:
|
||||
# gather all points together (joint normalization)
|
||||
nan_pts1 = invalid_to_nans(pts1, valid1, ndim=3)
|
||||
nan_pts2 = invalid_to_nans(pts2, valid2, ndim=3) if pts2 is not None else None
|
||||
all_pts = torch.cat((nan_pts1, nan_pts2), dim=1) if pts2 is not None else nan_pts1
|
||||
|
||||
# compute distance to origin
|
||||
all_dis = all_pts.norm(dim=-1)
|
||||
|
||||
if norm_mode == 'avg':
|
||||
norm_factor = all_dis.nanmean(dim=1)
|
||||
elif norm_mode == 'median':
|
||||
norm_factor = all_dis.nanmedian(dim=1).values.detach()
|
||||
elif norm_mode == 'sqrt':
|
||||
norm_factor = all_dis.sqrt().nanmean(dim=1)**2
|
||||
else:
|
||||
raise ValueError(f'bad {norm_mode=}')
|
||||
|
||||
norm_factor = norm_factor.clip(min=1e-8)
|
||||
while norm_factor.ndim < pts1.ndim:
|
||||
norm_factor.unsqueeze_(-1)
|
||||
|
||||
res = pts1 / norm_factor
|
||||
if pts2 is not None:
|
||||
res = (res, pts2 / norm_factor)
|
||||
return res
|
||||
|
||||
|
||||
@torch.no_grad()
|
||||
def get_joint_pointcloud_depth(z1, z2, valid_mask1, valid_mask2=None, quantile=0.5):
|
||||
# set invalid points to NaN
|
||||
_z1 = invalid_to_nans(z1, valid_mask1).reshape(len(z1), -1)
|
||||
_z2 = invalid_to_nans(z2, valid_mask2).reshape(len(z2), -1) if z2 is not None else None
|
||||
_z = torch.cat((_z1, _z2), dim=-1) if z2 is not None else _z1
|
||||
|
||||
# compute median depth overall (ignoring nans)
|
||||
if quantile == 0.5:
|
||||
shift_z = torch.nanmedian(_z, dim=-1).values
|
||||
else:
|
||||
shift_z = torch.nanquantile(_z, quantile, dim=-1)
|
||||
return shift_z # (B,)
|
||||
|
||||
|
||||
@torch.no_grad()
|
||||
def get_joint_pointcloud_center_scale(pts1, pts2, valid_mask1=None, valid_mask2=None, z_only=False, center=True):
|
||||
# set invalid points to NaN
|
||||
_pts1 = invalid_to_nans(pts1, valid_mask1).reshape(len(pts1), -1, 3)
|
||||
_pts2 = invalid_to_nans(pts2, valid_mask2).reshape(len(pts2), -1, 3) if pts2 is not None else None
|
||||
_pts = torch.cat((_pts1, _pts2), dim=1) if pts2 is not None else _pts1
|
||||
|
||||
# compute median center
|
||||
_center = torch.nanmedian(_pts, dim=1, keepdim=True).values # (B,1,3)
|
||||
if z_only:
|
||||
_center[..., :2] = 0 # do not center X and Y
|
||||
|
||||
# compute median norm
|
||||
_norm = ((_pts - _center) if center else _pts).norm(dim=-1)
|
||||
scale = torch.nanmedian(_norm, dim=1).values
|
||||
return _center[:, None, :, :], scale[:, None, None, None]
|
||||
|
||||
|
||||
def find_reciprocal_matches(P1, P2):
|
||||
"""
|
||||
returns 3 values:
|
||||
1 - reciprocal_in_P2: a boolean array of size P2.shape[0], a "True" value indicates a match
|
||||
2 - nn2_in_P1: a int array of size P2.shape[0], it contains the indexes of the closest points in P1
|
||||
3 - reciprocal_in_P2.sum(): the number of matches
|
||||
"""
|
||||
tree1 = KDTree(P1)
|
||||
tree2 = KDTree(P2)
|
||||
|
||||
_, nn1_in_P2 = tree2.query(P1, workers=8)
|
||||
_, nn2_in_P1 = tree1.query(P2, workers=8)
|
||||
|
||||
reciprocal_in_P1 = (nn2_in_P1[nn1_in_P2] == np.arange(len(nn1_in_P2)))
|
||||
reciprocal_in_P2 = (nn1_in_P2[nn2_in_P1] == np.arange(len(nn2_in_P1)))
|
||||
assert reciprocal_in_P1.sum() == reciprocal_in_P2.sum()
|
||||
return reciprocal_in_P2, nn2_in_P1, reciprocal_in_P2.sum()
|
||||
|
||||
|
||||
def get_med_dist_between_poses(poses):
|
||||
from scipy.spatial.distance import pdist
|
||||
return np.median(pdist([to_numpy(p[:3, 3]) for p in poses]))
|
||||
+170
@@ -0,0 +1,170 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# utilitary functions about images (loading/converting...)
|
||||
# --------------------------------------------------------
|
||||
import os
|
||||
import torch
|
||||
import numpy as np
|
||||
import PIL.Image
|
||||
from PIL.ImageOps import exif_transpose
|
||||
import torchvision.transforms as tvf
|
||||
os.environ["OPENCV_IO_ENABLE_OPENEXR"] = "1"
|
||||
import cv2 # noqa
|
||||
from PIL import Image, ImageOps
|
||||
|
||||
|
||||
def center_crop_pil_image(input_image, target_width=1024, target_height=576):
|
||||
w, h = input_image.size
|
||||
h_ratio = h / target_height
|
||||
w_ratio = w / target_width
|
||||
|
||||
if h_ratio > w_ratio:
|
||||
h = int(h / w_ratio)
|
||||
if h < target_height:
|
||||
h = target_height
|
||||
input_image = input_image.resize((target_width, h), Image.ANTIALIAS)
|
||||
else:
|
||||
w = int(w / h_ratio)
|
||||
if w < target_width:
|
||||
w = target_width
|
||||
input_image = input_image.resize((w, target_height), Image.ANTIALIAS)
|
||||
|
||||
return ImageOps.fit(input_image, (target_width, target_height), Image.BICUBIC)
|
||||
|
||||
try:
|
||||
from pillow_heif import register_heif_opener # noqa
|
||||
register_heif_opener()
|
||||
heif_support_enabled = True
|
||||
except ImportError:
|
||||
heif_support_enabled = False
|
||||
|
||||
ImgNorm = tvf.Compose([tvf.ToTensor(), tvf.Normalize((0.5, 0.5, 0.5), (0.5, 0.5, 0.5))])
|
||||
|
||||
|
||||
def imread_cv2(path, options=cv2.IMREAD_COLOR):
|
||||
""" Open an image or a depthmap with opencv-python.
|
||||
"""
|
||||
if path.endswith(('.exr', 'EXR')):
|
||||
options = cv2.IMREAD_ANYDEPTH
|
||||
img = cv2.imread(path, options)
|
||||
if img is None:
|
||||
raise IOError(f'Could not load image={path} with {options=}')
|
||||
if img.ndim == 3:
|
||||
img = cv2.cvtColor(img, cv2.COLOR_BGR2RGB)
|
||||
return img
|
||||
|
||||
|
||||
def rgb(ftensor, true_shape=None):
|
||||
if isinstance(ftensor, list):
|
||||
return [rgb(x, true_shape=true_shape) for x in ftensor]
|
||||
if isinstance(ftensor, torch.Tensor):
|
||||
ftensor = ftensor.detach().cpu().numpy() # H,W,3
|
||||
if ftensor.ndim == 3 and ftensor.shape[0] == 3:
|
||||
ftensor = ftensor.transpose(1, 2, 0)
|
||||
elif ftensor.ndim == 4 and ftensor.shape[1] == 3:
|
||||
ftensor = ftensor.transpose(0, 2, 3, 1)
|
||||
if true_shape is not None:
|
||||
H, W = true_shape
|
||||
ftensor = ftensor[:H, :W]
|
||||
if ftensor.dtype == np.uint8:
|
||||
img = np.float32(ftensor) / 255
|
||||
else:
|
||||
img = (ftensor * 0.5) + 0.5
|
||||
return img.clip(min=0, max=1)
|
||||
|
||||
|
||||
def _resize_pil_image(img, long_edge_size):
|
||||
S = max(img.size)
|
||||
if S > long_edge_size:
|
||||
interp = PIL.Image.LANCZOS
|
||||
elif S <= long_edge_size:
|
||||
interp = PIL.Image.BICUBIC
|
||||
new_size = tuple(int(round(x*long_edge_size/S)) for x in img.size)
|
||||
return img.resize(new_size, interp)
|
||||
|
||||
|
||||
def load_images(folder_or_list, size, square_ok=False,force_1024 = False):
|
||||
""" open and convert all images in a list or folder to proper input format for DUSt3R
|
||||
"""
|
||||
if isinstance(folder_or_list, str):
|
||||
print(f'>> Loading images from {folder_or_list}')
|
||||
root, folder_content = folder_or_list, sorted(os.listdir(folder_or_list))
|
||||
|
||||
elif isinstance(folder_or_list, list):
|
||||
print(f'>> Loading a list of {len(folder_or_list)} images')
|
||||
root, folder_content = '', folder_or_list
|
||||
|
||||
else:
|
||||
raise ValueError(f'bad {folder_or_list=} ({type(folder_or_list)})')
|
||||
|
||||
supported_images_extensions = ['.jpg', '.jpeg', '.png']
|
||||
if heif_support_enabled:
|
||||
supported_images_extensions += ['.heic', '.heif']
|
||||
supported_images_extensions = tuple(supported_images_extensions)
|
||||
|
||||
imgs = []
|
||||
for path in folder_content:
|
||||
if not path.lower().endswith(supported_images_extensions):
|
||||
continue
|
||||
img = exif_transpose(PIL.Image.open(os.path.join(root, path))).convert('RGB')
|
||||
if force_1024:
|
||||
img = center_crop_pil_image(img)
|
||||
img_ori = img
|
||||
W1, H1 = img.size
|
||||
if size == 224:
|
||||
# resize short side to 224 (then crop)
|
||||
img = _resize_pil_image(img, round(size * max(W1/H1, H1/W1)))
|
||||
else:
|
||||
# resize long side to 512
|
||||
img = _resize_pil_image(img, size)
|
||||
W, H = img.size
|
||||
cx, cy = W//2, H//2
|
||||
if size == 224:
|
||||
half = min(cx, cy)
|
||||
img = img.crop((cx-half, cy-half, cx+half, cy+half))
|
||||
else:
|
||||
halfw, halfh = ((2*cx)//16)*8, ((2*cy)//16)*8
|
||||
if not (square_ok) and W == H:
|
||||
halfh = 3*halfw/4
|
||||
img = img.crop((cx-halfw, cy-halfh, cx+halfw, cy+halfh))
|
||||
|
||||
W2, H2 = img.size
|
||||
print(f' - adding {path} with resolution {W1}x{H1} --> {W2}x{H2}')
|
||||
imgs.append(dict(img=ImgNorm(img)[None], true_shape=np.int32(
|
||||
[img.size[::-1]]), idx=len(imgs), instance=str(len(imgs)), img_ori=ImgNorm(img_ori)[None], ))
|
||||
|
||||
assert imgs, 'no images foud at '+root
|
||||
print(f' (Found {len(imgs)} images)')
|
||||
return imgs
|
||||
|
||||
def load_images_base(folder_or_list, folder_name, size, square_ok=False):
|
||||
""" open and convert all images in a list or folder to proper input format for DUSt3R
|
||||
"""
|
||||
|
||||
imgs = []
|
||||
for path in folder_or_list:
|
||||
img = exif_transpose(PIL.Image.open(os.path.join(folder_name, path))).convert('RGB')
|
||||
W1, H1 = img.size
|
||||
if size == 224:
|
||||
# resize short side to 224 (then crop)
|
||||
img = _resize_pil_image(img, round(size * max(W1/H1, H1/W1)))
|
||||
else:
|
||||
# resize long side to 512
|
||||
img = _resize_pil_image(img, size)
|
||||
W, H = img.size
|
||||
cx, cy = W//2, H//2
|
||||
if size == 224:
|
||||
half = min(cx, cy)
|
||||
img = img.crop((cx-half, cy-half, cx+half, cy+half))
|
||||
else:
|
||||
halfw, halfh = ((2*cx)//16)*8, ((2*cy)//16)*8
|
||||
if not (square_ok) and W == H:
|
||||
halfh = 3*halfw/4
|
||||
img = img.crop((cx-halfw, cy-halfh, cx+halfw, cy+halfh))
|
||||
imgs.append(dict(img=ImgNorm(img)[None], true_shape=np.int32(
|
||||
[img.size[::-1]]), idx=len(imgs), instance=str(len(imgs)), ))
|
||||
|
||||
return imgs
|
||||
|
||||
+121
@@ -0,0 +1,121 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# utilitary functions for DUSt3R
|
||||
# --------------------------------------------------------
|
||||
import torch
|
||||
|
||||
|
||||
def fill_default_args(kwargs, func):
|
||||
import inspect # a bit hacky but it works reliably
|
||||
signature = inspect.signature(func)
|
||||
|
||||
for k, v in signature.parameters.items():
|
||||
if v.default is inspect.Parameter.empty:
|
||||
continue
|
||||
kwargs.setdefault(k, v.default)
|
||||
|
||||
return kwargs
|
||||
|
||||
|
||||
def freeze_all_params(modules):
|
||||
for module in modules:
|
||||
try:
|
||||
for n, param in module.named_parameters():
|
||||
param.requires_grad = False
|
||||
except AttributeError:
|
||||
# module is directly a parameter
|
||||
module.requires_grad = False
|
||||
|
||||
|
||||
def is_symmetrized(gt1, gt2):
|
||||
x = gt1['instance']
|
||||
y = gt2['instance']
|
||||
if len(x) == len(y) and len(x) == 1:
|
||||
return False # special case of batchsize 1
|
||||
ok = True
|
||||
for i in range(0, len(x), 2):
|
||||
ok = ok and (x[i] == y[i+1]) and (x[i+1] == y[i])
|
||||
return ok
|
||||
|
||||
|
||||
def flip(tensor):
|
||||
""" flip so that tensor[0::2] <=> tensor[1::2] """
|
||||
return torch.stack((tensor[1::2], tensor[0::2]), dim=1).flatten(0, 1)
|
||||
|
||||
|
||||
def interleave(tensor1, tensor2):
|
||||
res1 = torch.stack((tensor1, tensor2), dim=1).flatten(0, 1)
|
||||
res2 = torch.stack((tensor2, tensor1), dim=1).flatten(0, 1)
|
||||
return res1, res2
|
||||
|
||||
|
||||
def transpose_to_landscape(head, activate=True):
|
||||
""" Predict in the correct aspect-ratio,
|
||||
then transpose the result in landscape
|
||||
and stack everything back together.
|
||||
"""
|
||||
def wrapper_no(decout, true_shape):
|
||||
B = len(true_shape)
|
||||
assert true_shape[0:1].allclose(true_shape), 'true_shape must be all identical'
|
||||
H, W = true_shape[0].cpu().tolist()
|
||||
res = head(decout, (H, W))
|
||||
return res
|
||||
|
||||
def wrapper_yes(decout, true_shape):
|
||||
B = len(true_shape)
|
||||
# by definition, the batch is in landscape mode so W >= H
|
||||
H, W = int(true_shape.min()), int(true_shape.max())
|
||||
|
||||
height, width = true_shape.T
|
||||
is_landscape = (width >= height)
|
||||
is_portrait = ~is_landscape
|
||||
|
||||
# true_shape = true_shape.cpu()
|
||||
if is_landscape.all():
|
||||
return head(decout, (H, W))
|
||||
if is_portrait.all():
|
||||
return transposed(head(decout, (W, H)))
|
||||
|
||||
# batch is a mix of both portraint & landscape
|
||||
def selout(ar): return [d[ar] for d in decout]
|
||||
l_result = head(selout(is_landscape), (H, W))
|
||||
p_result = transposed(head(selout(is_portrait), (W, H)))
|
||||
|
||||
# allocate full result
|
||||
result = {}
|
||||
for k in l_result | p_result:
|
||||
x = l_result[k].new(B, *l_result[k].shape[1:])
|
||||
x[is_landscape] = l_result[k]
|
||||
x[is_portrait] = p_result[k]
|
||||
result[k] = x
|
||||
|
||||
return result
|
||||
|
||||
return wrapper_yes if activate else wrapper_no
|
||||
|
||||
|
||||
def transposed(dic):
|
||||
return {k: v.swapaxes(1, 2) for k, v in dic.items()}
|
||||
|
||||
|
||||
def invalid_to_nans(arr, valid_mask, ndim=999):
|
||||
if valid_mask is not None:
|
||||
arr = arr.clone()
|
||||
arr[~valid_mask] = float('nan')
|
||||
if arr.ndim > ndim:
|
||||
arr = arr.flatten(-2 - (arr.ndim - ndim), -2)
|
||||
return arr
|
||||
|
||||
|
||||
def invalid_to_zeros(arr, valid_mask, ndim=999):
|
||||
if valid_mask is not None:
|
||||
arr = arr.clone()
|
||||
arr[~valid_mask] = 0
|
||||
nnz = valid_mask.view(len(valid_mask), -1).sum(1)
|
||||
else:
|
||||
nnz = arr.numel() // len(arr) if len(arr) else 0 # number of point per image
|
||||
if arr.ndim > ndim:
|
||||
arr = arr.flatten(-2 - (arr.ndim - ndim), -2)
|
||||
return arr, nnz
|
||||
@@ -0,0 +1,19 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# CroCo submodule import
|
||||
# --------------------------------------------------------
|
||||
|
||||
import sys
|
||||
import os.path as path
|
||||
HERE_PATH = path.normpath(path.dirname(__file__))
|
||||
CROCO_REPO_PATH = path.normpath(path.join(HERE_PATH, '../../croco'))
|
||||
CROCO_MODELS_PATH = path.join(CROCO_REPO_PATH, 'models')
|
||||
# check the presence of models directory in repo to be sure its cloned
|
||||
if path.isdir(CROCO_MODELS_PATH):
|
||||
# workaround for sibling import
|
||||
sys.path.insert(0, CROCO_REPO_PATH)
|
||||
else:
|
||||
raise ImportError(f"croco is not initialized, could not find: {CROCO_MODELS_PATH}.\n "
|
||||
"Did you forget to run 'git submodule update --init --recursive' ?")
|
||||
+320
@@ -0,0 +1,320 @@
|
||||
# Copyright (C) 2024-present Naver Corporation. All rights reserved.
|
||||
# Licensed under CC BY-NC-SA 4.0 (non-commercial use only).
|
||||
#
|
||||
# --------------------------------------------------------
|
||||
# Visualization utilities using trimesh
|
||||
# --------------------------------------------------------
|
||||
import PIL.Image
|
||||
import numpy as np
|
||||
from scipy.spatial.transform import Rotation
|
||||
import torch
|
||||
|
||||
from dust3r.utils.geometry import geotrf, get_med_dist_between_poses
|
||||
from dust3r.utils.device import to_numpy
|
||||
from dust3r.utils.image import rgb
|
||||
|
||||
try:
|
||||
import trimesh
|
||||
except ImportError:
|
||||
print('/!\\ module trimesh is not installed, cannot visualize results /!\\')
|
||||
|
||||
|
||||
def cat_3d(vecs):
|
||||
if isinstance(vecs, (np.ndarray, torch.Tensor)):
|
||||
vecs = [vecs]
|
||||
return np.concatenate([p.reshape(-1, 3) for p in to_numpy(vecs)])
|
||||
|
||||
|
||||
def show_raw_pointcloud(pts3d, colors, point_size=2):
|
||||
scene = trimesh.Scene()
|
||||
|
||||
pct = trimesh.PointCloud(cat_3d(pts3d), colors=cat_3d(colors))
|
||||
scene.add_geometry(pct)
|
||||
|
||||
scene.show(line_settings={'point_size': point_size})
|
||||
|
||||
|
||||
def pts3d_to_trimesh(img, pts3d, valid=None):
|
||||
H, W, THREE = img.shape
|
||||
assert THREE == 3
|
||||
assert img.shape == pts3d.shape
|
||||
|
||||
vertices = pts3d.reshape(-1, 3)
|
||||
|
||||
# make squares: each pixel == 2 triangles
|
||||
idx = np.arange(len(vertices)).reshape(H, W)
|
||||
idx1 = idx[:-1, :-1].ravel() # top-left corner
|
||||
idx2 = idx[:-1, +1:].ravel() # right-left corner
|
||||
idx3 = idx[+1:, :-1].ravel() # bottom-left corner
|
||||
idx4 = idx[+1:, +1:].ravel() # bottom-right corner
|
||||
faces = np.concatenate((
|
||||
np.c_[idx1, idx2, idx3],
|
||||
np.c_[idx3, idx2, idx1], # same triangle, but backward (cheap solution to cancel face culling)
|
||||
np.c_[idx2, idx3, idx4],
|
||||
np.c_[idx4, idx3, idx2], # same triangle, but backward (cheap solution to cancel face culling)
|
||||
), axis=0)
|
||||
|
||||
# prepare triangle colors
|
||||
face_colors = np.concatenate((
|
||||
img[:-1, :-1].reshape(-1, 3),
|
||||
img[:-1, :-1].reshape(-1, 3),
|
||||
img[+1:, +1:].reshape(-1, 3),
|
||||
img[+1:, +1:].reshape(-1, 3)
|
||||
), axis=0)
|
||||
|
||||
# remove invalid faces
|
||||
if valid is not None:
|
||||
assert valid.shape == (H, W)
|
||||
valid_idxs = valid.ravel()
|
||||
valid_faces = valid_idxs[faces].all(axis=-1)
|
||||
faces = faces[valid_faces]
|
||||
face_colors = face_colors[valid_faces]
|
||||
|
||||
assert len(faces) == len(face_colors)
|
||||
return dict(vertices=vertices, face_colors=face_colors, faces=faces)
|
||||
|
||||
|
||||
def cat_meshes(meshes):
|
||||
vertices, faces, colors = zip(*[(m['vertices'], m['faces'], m['face_colors']) for m in meshes])
|
||||
n_vertices = np.cumsum([0]+[len(v) for v in vertices])
|
||||
for i in range(len(faces)):
|
||||
faces[i][:] += n_vertices[i]
|
||||
|
||||
vertices = np.concatenate(vertices)
|
||||
colors = np.concatenate(colors)
|
||||
faces = np.concatenate(faces)
|
||||
return dict(vertices=vertices, face_colors=colors, faces=faces)
|
||||
|
||||
|
||||
def show_duster_pairs(view1, view2, pred1, pred2):
|
||||
import matplotlib.pyplot as pl
|
||||
pl.ion()
|
||||
|
||||
for e in range(len(view1['instance'])):
|
||||
i = view1['idx'][e]
|
||||
j = view2['idx'][e]
|
||||
img1 = rgb(view1['img'][e])
|
||||
img2 = rgb(view2['img'][e])
|
||||
conf1 = pred1['conf'][e].squeeze()
|
||||
conf2 = pred2['conf'][e].squeeze()
|
||||
score = conf1.mean()*conf2.mean()
|
||||
print(f">> Showing pair #{e} {i}-{j} {score=:g}")
|
||||
pl.clf()
|
||||
pl.subplot(221).imshow(img1)
|
||||
pl.subplot(223).imshow(img2)
|
||||
pl.subplot(222).imshow(conf1, vmin=1, vmax=30)
|
||||
pl.subplot(224).imshow(conf2, vmin=1, vmax=30)
|
||||
pts1 = pred1['pts3d'][e]
|
||||
pts2 = pred2['pts3d_in_other_view'][e]
|
||||
pl.subplots_adjust(0, 0, 1, 1, 0, 0)
|
||||
if input('show pointcloud? (y/n) ') == 'y':
|
||||
show_raw_pointcloud(cat(pts1, pts2), cat(img1, img2), point_size=5)
|
||||
|
||||
|
||||
def auto_cam_size(im_poses):
|
||||
return 0.1 * get_med_dist_between_poses(im_poses)
|
||||
|
||||
|
||||
class SceneViz:
|
||||
def __init__(self):
|
||||
self.scene = trimesh.Scene()
|
||||
|
||||
def add_pointcloud(self, pts3d, color, mask=None):
|
||||
pts3d = to_numpy(pts3d)
|
||||
mask = to_numpy(mask)
|
||||
if mask is None:
|
||||
mask = [slice(None)] * len(pts3d)
|
||||
pts = np.concatenate([p[m] for p, m in zip(pts3d, mask)])
|
||||
pct = trimesh.PointCloud(pts.reshape(-1, 3))
|
||||
|
||||
if isinstance(color, (list, np.ndarray, torch.Tensor)):
|
||||
color = to_numpy(color)
|
||||
col = np.concatenate([p[m] for p, m in zip(color, mask)])
|
||||
assert col.shape == pts.shape
|
||||
pct.visual.vertex_colors = uint8(col.reshape(-1, 3))
|
||||
else:
|
||||
assert len(color) == 3
|
||||
pct.visual.vertex_colors = np.broadcast_to(uint8(color), pts.shape)
|
||||
|
||||
self.scene.add_geometry(pct)
|
||||
return self
|
||||
|
||||
def add_camera(self, pose_c2w, focal=None, color=(0, 0, 0), image=None, imsize=None, cam_size=0.03):
|
||||
pose_c2w, focal, color, image = to_numpy((pose_c2w, focal, color, image))
|
||||
add_scene_cam(self.scene, pose_c2w, color, image, focal, screen_width=cam_size)
|
||||
return self
|
||||
|
||||
def add_cameras(self, poses, focals=None, images=None, imsizes=None, colors=None, **kw):
|
||||
def get(arr, idx): return None if arr is None else arr[idx]
|
||||
for i, pose_c2w in enumerate(poses):
|
||||
self.add_camera(pose_c2w, get(focals, i), image=get(images, i),
|
||||
color=get(colors, i), imsize=get(imsizes, i), **kw)
|
||||
return self
|
||||
|
||||
def show(self, point_size=2):
|
||||
self.scene.show(line_settings={'point_size': point_size})
|
||||
|
||||
|
||||
def show_raw_pointcloud_with_cams(imgs, pts3d, mask, focals, cams2world,
|
||||
point_size=2, cam_size=0.05, cam_color=None):
|
||||
""" Visualization of a pointcloud with cameras
|
||||
imgs = (N, H, W, 3) or N-size list of [(H,W,3), ...]
|
||||
pts3d = (N, H, W, 3) or N-size list of [(H,W,3), ...]
|
||||
focals = (N,) or N-size list of [focal, ...]
|
||||
cams2world = (N,4,4) or N-size list of [(4,4), ...]
|
||||
"""
|
||||
assert len(pts3d) == len(mask) <= len(imgs) <= len(cams2world) == len(focals)
|
||||
pts3d = to_numpy(pts3d)
|
||||
imgs = to_numpy(imgs)
|
||||
focals = to_numpy(focals)
|
||||
cams2world = to_numpy(cams2world)
|
||||
|
||||
scene = trimesh.Scene()
|
||||
|
||||
# full pointcloud
|
||||
pts = np.concatenate([p[m] for p, m in zip(pts3d, mask)])
|
||||
col = np.concatenate([p[m] for p, m in zip(imgs, mask)])
|
||||
pct = trimesh.PointCloud(pts.reshape(-1, 3), colors=col.reshape(-1, 3))
|
||||
scene.add_geometry(pct)
|
||||
|
||||
# add each camera
|
||||
for i, pose_c2w in enumerate(cams2world):
|
||||
if isinstance(cam_color, list):
|
||||
camera_edge_color = cam_color[i]
|
||||
else:
|
||||
camera_edge_color = cam_color or CAM_COLORS[i % len(CAM_COLORS)]
|
||||
add_scene_cam(scene, pose_c2w, camera_edge_color,
|
||||
imgs[i] if i < len(imgs) else None, focals[i], screen_width=cam_size)
|
||||
|
||||
scene.show(line_settings={'point_size': point_size})
|
||||
|
||||
|
||||
def add_scene_cam(scene, pose_c2w, edge_color, image=None, focal=None, imsize=None, screen_width=0.03):
|
||||
|
||||
if image is not None:
|
||||
H, W, THREE = image.shape
|
||||
assert THREE == 3
|
||||
if image.dtype != np.uint8:
|
||||
image = np.uint8(255*image)
|
||||
elif imsize is not None:
|
||||
W, H = imsize
|
||||
elif focal is not None:
|
||||
H = W = focal / 1.1
|
||||
else:
|
||||
H = W = 1
|
||||
|
||||
if focal is None:
|
||||
focal = min(H, W) * 1.1 # default value
|
||||
elif isinstance(focal, np.ndarray):
|
||||
focal = focal[0]
|
||||
|
||||
# create fake camera
|
||||
height = focal * screen_width / H
|
||||
width = screen_width * 0.5**0.5
|
||||
rot45 = np.eye(4)
|
||||
rot45[:3, :3] = Rotation.from_euler('z', np.deg2rad(45)).as_matrix()
|
||||
rot45[2, 3] = -height # set the tip of the cone = optical center
|
||||
aspect_ratio = np.eye(4)
|
||||
aspect_ratio[0, 0] = W/H
|
||||
transform = pose_c2w @ OPENGL @ aspect_ratio @ rot45
|
||||
cam = trimesh.creation.cone(width, height, sections=4) # , transform=transform)
|
||||
|
||||
# this is the image
|
||||
if image is not None:
|
||||
vertices = geotrf(transform, cam.vertices[[4, 5, 1, 3]])
|
||||
faces = np.array([[0, 1, 2], [0, 2, 3], [2, 1, 0], [3, 2, 0]])
|
||||
img = trimesh.Trimesh(vertices=vertices, faces=faces)
|
||||
uv_coords = np.float32([[0, 0], [1, 0], [1, 1], [0, 1]])
|
||||
img.visual = trimesh.visual.TextureVisuals(uv_coords, image=PIL.Image.fromarray(image))
|
||||
scene.add_geometry(img)
|
||||
|
||||
# this is the camera mesh
|
||||
rot2 = np.eye(4)
|
||||
rot2[:3, :3] = Rotation.from_euler('z', np.deg2rad(2)).as_matrix()
|
||||
vertices = np.r_[cam.vertices, 0.95*cam.vertices, geotrf(rot2, cam.vertices)]
|
||||
vertices = geotrf(transform, vertices)
|
||||
faces = []
|
||||
for face in cam.faces:
|
||||
if 0 in face:
|
||||
continue
|
||||
a, b, c = face
|
||||
a2, b2, c2 = face + len(cam.vertices)
|
||||
a3, b3, c3 = face + 2*len(cam.vertices)
|
||||
|
||||
# add 3 pseudo-edges
|
||||
faces.append((a, b, b2))
|
||||
faces.append((a, a2, c))
|
||||
faces.append((c2, b, c))
|
||||
|
||||
faces.append((a, b, b3))
|
||||
faces.append((a, a3, c))
|
||||
faces.append((c3, b, c))
|
||||
|
||||
# no culling
|
||||
faces += [(c, b, a) for a, b, c in faces]
|
||||
|
||||
cam = trimesh.Trimesh(vertices=vertices, faces=faces)
|
||||
cam.visual.face_colors[:, :3] = edge_color
|
||||
scene.add_geometry(cam)
|
||||
|
||||
|
||||
def cat(a, b):
|
||||
return np.concatenate((a.reshape(-1, 3), b.reshape(-1, 3)))
|
||||
|
||||
|
||||
OPENGL = np.array([[1, 0, 0, 0],
|
||||
[0, -1, 0, 0],
|
||||
[0, 0, -1, 0],
|
||||
[0, 0, 0, 1]])
|
||||
|
||||
|
||||
CAM_COLORS = [(255, 0, 0), (0, 0, 255), (0, 255, 0), (255, 0, 255), (255, 204, 0), (0, 204, 204),
|
||||
(128, 255, 255), (255, 128, 255), (255, 255, 128), (0, 0, 0), (128, 128, 128)]
|
||||
|
||||
|
||||
def uint8(colors):
|
||||
if not isinstance(colors, np.ndarray):
|
||||
colors = np.array(colors)
|
||||
if np.issubdtype(colors.dtype, np.floating):
|
||||
colors *= 255
|
||||
assert 0 <= colors.min() and colors.max() < 256
|
||||
return np.uint8(colors)
|
||||
|
||||
|
||||
def segment_sky(image):
|
||||
import cv2
|
||||
from scipy import ndimage
|
||||
|
||||
# Convert to HSV
|
||||
image = to_numpy(image)
|
||||
if np.issubdtype(image.dtype, np.floating):
|
||||
image = np.uint8(255*image.clip(min=0, max=1))
|
||||
hsv = cv2.cvtColor(image, cv2.COLOR_BGR2HSV)
|
||||
|
||||
# Define range for blue color and create mask
|
||||
lower_blue = np.array([0, 0, 100])
|
||||
upper_blue = np.array([30, 255, 255])
|
||||
mask = cv2.inRange(hsv, lower_blue, upper_blue).view(bool)
|
||||
|
||||
# add luminous gray
|
||||
mask |= (hsv[:, :, 1] < 10) & (hsv[:, :, 2] > 150)
|
||||
mask |= (hsv[:, :, 1] < 30) & (hsv[:, :, 2] > 180)
|
||||
mask |= (hsv[:, :, 1] < 50) & (hsv[:, :, 2] > 220)
|
||||
|
||||
# Morphological operations
|
||||
kernel = np.ones((5, 5), np.uint8)
|
||||
mask2 = ndimage.binary_opening(mask, structure=kernel)
|
||||
|
||||
# keep only largest CC
|
||||
_, labels, stats, _ = cv2.connectedComponentsWithStats(mask2.view(np.uint8), connectivity=8)
|
||||
cc_sizes = stats[1:, cv2.CC_STAT_AREA]
|
||||
order = cc_sizes.argsort()[::-1] # bigger first
|
||||
i = 0
|
||||
selection = []
|
||||
while i < len(order) and cc_sizes[order[i]] > cc_sizes[order[0]] / 2:
|
||||
selection.append(1 + order[i])
|
||||
i += 1
|
||||
mask3 = np.in1d(labels, selection).reshape(labels.shape)
|
||||
|
||||
# Apply mask
|
||||
return torch.from_numpy(mask3)
|
||||
@@ -0,0 +1,100 @@
|
||||
# adopted from
|
||||
# https://github.com/openai/improved-diffusion/blob/main/improved_diffusion/gaussian_diffusion.py
|
||||
# and
|
||||
# https://github.com/lucidrains/denoising-diffusion-pytorch/blob/7706bdfc6f527f58d33f84b7b522e61e6e3164b3/denoising_diffusion_pytorch/denoising_diffusion_pytorch.py
|
||||
# and
|
||||
# https://github.com/openai/guided-diffusion/blob/0ba878e517b276c45d1195eb29f6f5f72659a05b/guided_diffusion/nn.py
|
||||
#
|
||||
# thanks!
|
||||
|
||||
import torch.nn as nn
|
||||
from utils.diffusion_utils import instantiate_from_config
|
||||
|
||||
|
||||
def disabled_train(self, mode=True):
|
||||
"""Overwrite model.train with this function to make sure train/eval mode
|
||||
does not change anymore."""
|
||||
return self
|
||||
|
||||
def zero_module(module):
|
||||
"""
|
||||
Zero out the parameters of a module and return it.
|
||||
"""
|
||||
for p in module.parameters():
|
||||
p.detach().zero_()
|
||||
return module
|
||||
|
||||
def scale_module(module, scale):
|
||||
"""
|
||||
Scale the parameters of a module and return it.
|
||||
"""
|
||||
for p in module.parameters():
|
||||
p.detach().mul_(scale)
|
||||
return module
|
||||
|
||||
|
||||
def conv_nd(dims, *args, **kwargs):
|
||||
"""
|
||||
Create a 1D, 2D, or 3D convolution module.
|
||||
"""
|
||||
if dims == 1:
|
||||
return nn.Conv1d(*args, **kwargs)
|
||||
elif dims == 2:
|
||||
return nn.Conv2d(*args, **kwargs)
|
||||
elif dims == 3:
|
||||
return nn.Conv3d(*args, **kwargs)
|
||||
raise ValueError(f"unsupported dimensions: {dims}")
|
||||
|
||||
|
||||
def linear(*args, **kwargs):
|
||||
"""
|
||||
Create a linear module.
|
||||
"""
|
||||
return nn.Linear(*args, **kwargs)
|
||||
|
||||
|
||||
def avg_pool_nd(dims, *args, **kwargs):
|
||||
"""
|
||||
Create a 1D, 2D, or 3D average pooling module.
|
||||
"""
|
||||
if dims == 1:
|
||||
return nn.AvgPool1d(*args, **kwargs)
|
||||
elif dims == 2:
|
||||
return nn.AvgPool2d(*args, **kwargs)
|
||||
elif dims == 3:
|
||||
return nn.AvgPool3d(*args, **kwargs)
|
||||
raise ValueError(f"unsupported dimensions: {dims}")
|
||||
|
||||
|
||||
def nonlinearity(type='silu'):
|
||||
if type == 'silu':
|
||||
return nn.SiLU()
|
||||
elif type == 'leaky_relu':
|
||||
return nn.LeakyReLU()
|
||||
|
||||
|
||||
class GroupNormSpecific(nn.GroupNorm):
|
||||
def forward(self, x):
|
||||
return super().forward(x.float()).type(x.dtype)
|
||||
|
||||
|
||||
def normalization(channels, num_groups=32):
|
||||
"""
|
||||
Make a standard normalization layer.
|
||||
:param channels: number of input channels.
|
||||
:return: an nn.Module for normalization.
|
||||
"""
|
||||
return GroupNormSpecific(num_groups, channels)
|
||||
|
||||
|
||||
class HybridConditioner(nn.Module):
|
||||
|
||||
def __init__(self, c_concat_config, c_crossattn_config):
|
||||
super().__init__()
|
||||
self.concat_conditioner = instantiate_from_config(c_concat_config)
|
||||
self.crossattn_conditioner = instantiate_from_config(c_crossattn_config)
|
||||
|
||||
def forward(self, c_concat, c_crossattn):
|
||||
c_concat = self.concat_conditioner(c_concat)
|
||||
c_crossattn = self.crossattn_conditioner(c_crossattn)
|
||||
return {'c_concat': [c_concat], 'c_crossattn': [c_crossattn]}
|
||||
@@ -0,0 +1,94 @@
|
||||
import math
|
||||
from inspect import isfunction
|
||||
import torch
|
||||
from torch import nn
|
||||
import torch.distributed as dist
|
||||
|
||||
|
||||
def gather_data(data, return_np=True):
|
||||
''' gather data from multiple processes to one list '''
|
||||
data_list = [torch.zeros_like(data) for _ in range(dist.get_world_size())]
|
||||
dist.all_gather(data_list, data) # gather not supported with NCCL
|
||||
if return_np:
|
||||
data_list = [data.cpu().numpy() for data in data_list]
|
||||
return data_list
|
||||
|
||||
def autocast(f):
|
||||
def do_autocast(*args, **kwargs):
|
||||
with torch.cuda.amp.autocast(enabled=True,
|
||||
dtype=torch.get_autocast_gpu_dtype(),
|
||||
cache_enabled=torch.is_autocast_cache_enabled()):
|
||||
return f(*args, **kwargs)
|
||||
return do_autocast
|
||||
|
||||
|
||||
def extract_into_tensor(a, t, x_shape):
|
||||
b, *_ = t.shape
|
||||
out = a.gather(-1, t)
|
||||
return out.reshape(b, *((1,) * (len(x_shape) - 1)))
|
||||
|
||||
|
||||
def noise_like(shape, device, repeat=False):
|
||||
repeat_noise = lambda: torch.randn((1, *shape[1:]), device=device).repeat(shape[0], *((1,) * (len(shape) - 1)))
|
||||
noise = lambda: torch.randn(shape, device=device)
|
||||
return repeat_noise() if repeat else noise()
|
||||
|
||||
|
||||
def default(val, d):
|
||||
if exists(val):
|
||||
return val
|
||||
return d() if isfunction(d) else d
|
||||
|
||||
def exists(val):
|
||||
return val is not None
|
||||
|
||||
def identity(*args, **kwargs):
|
||||
return nn.Identity()
|
||||
|
||||
def uniq(arr):
|
||||
return{el: True for el in arr}.keys()
|
||||
|
||||
def mean_flat(tensor):
|
||||
"""
|
||||
Take the mean over all non-batch dimensions.
|
||||
"""
|
||||
return tensor.mean(dim=list(range(1, len(tensor.shape))))
|
||||
|
||||
def ismap(x):
|
||||
if not isinstance(x, torch.Tensor):
|
||||
return False
|
||||
return (len(x.shape) == 4) and (x.shape[1] > 3)
|
||||
|
||||
def isimage(x):
|
||||
if not isinstance(x,torch.Tensor):
|
||||
return False
|
||||
return (len(x.shape) == 4) and (x.shape[1] == 3 or x.shape[1] == 1)
|
||||
|
||||
def max_neg_value(t):
|
||||
return -torch.finfo(t.dtype).max
|
||||
|
||||
def shape_to_str(x):
|
||||
shape_str = "x".join([str(x) for x in x.shape])
|
||||
return shape_str
|
||||
|
||||
def init_(tensor):
|
||||
dim = tensor.shape[-1]
|
||||
std = 1 / math.sqrt(dim)
|
||||
tensor.uniform_(-std, std)
|
||||
return tensor
|
||||
|
||||
ckpt = torch.utils.checkpoint.checkpoint
|
||||
def checkpoint(func, inputs, params, flag):
|
||||
"""
|
||||
Evaluate a function without caching intermediate activations, allowing for
|
||||
reduced memory at the expense of extra compute in the backward pass.
|
||||
:param func: the function to evaluate.
|
||||
:param inputs: the argument sequence to pass to `func`.
|
||||
:param params: a sequence of parameters `func` depends on but does not
|
||||
explicitly take as arguments.
|
||||
:param flag: if False, disable gradient checkpointing.
|
||||
"""
|
||||
if flag:
|
||||
return ckpt(func, *inputs, use_reentrant=False)
|
||||
else:
|
||||
return func(*inputs)
|
||||
@@ -0,0 +1,167 @@
|
||||
import os
|
||||
import random
|
||||
from tqdm import tqdm
|
||||
import pandas as pd
|
||||
from decord import VideoReader, cpu
|
||||
|
||||
import torch
|
||||
from torch.utils.data import Dataset
|
||||
from torch.utils.data import DataLoader
|
||||
from torchvision import transforms
|
||||
#import torchvision.transforms._transforms_video as transforms_video
|
||||
def string_not_contains_any(substrings, target_string):
|
||||
return not any(substring in target_string for substring in substrings)
|
||||
|
||||
word = ['digital', 'Digital', 'DIGITAL', 'concept', 'Concept', 'CONCEPT', 'abstract', 'Abstract', 'ABSTRACT', 'particle', 'Particle', 'PARTICLE', 'loop', 'Loop','LOOP']
|
||||
|
||||
class WebVid(Dataset):
|
||||
"""
|
||||
WebVid Dataset.
|
||||
Assumes webvid data is structured as follows.
|
||||
Webvid/
|
||||
videos/
|
||||
000001_000050/ ($page_dir)
|
||||
1.mp4 (videoid.mp4)
|
||||
...
|
||||
5000.mp4
|
||||
...
|
||||
"""
|
||||
def __init__(self,
|
||||
meta_path,
|
||||
data_dir,
|
||||
subsample=None,
|
||||
video_length=16,
|
||||
resolution=[256, 512],
|
||||
frame_stride=1,
|
||||
frame_stride_min=1,
|
||||
spatial_transform=None,
|
||||
crop_resolution=None,
|
||||
fps_max=None,
|
||||
load_raw_resolution=False,
|
||||
fixed_fps=None,
|
||||
random_fs=False,
|
||||
filter_CG=False,
|
||||
human_dynamic=False,
|
||||
sample_basedon_keyframe=False,
|
||||
):
|
||||
self.meta_path = meta_path
|
||||
self.data_dir = data_dir
|
||||
self.subsample = subsample
|
||||
self.video_length = video_length
|
||||
self.resolution = [resolution, resolution] if isinstance(resolution, int) else resolution
|
||||
self.fps_max = fps_max
|
||||
self.frame_stride = frame_stride
|
||||
self.frame_stride_min = frame_stride_min
|
||||
self.fixed_fps = fixed_fps
|
||||
self.load_raw_resolution = load_raw_resolution
|
||||
self.random_fs = random_fs
|
||||
self.filter_CG = filter_CG
|
||||
self.human_dynamic = human_dynamic
|
||||
self.sample_basedon_keyframe = sample_basedon_keyframe
|
||||
self._load_metadata()
|
||||
if spatial_transform is not None:
|
||||
if spatial_transform == "random_crop":
|
||||
self.spatial_transform = transforms.RandomCrop(crop_resolution)
|
||||
elif spatial_transform == "center_crop":
|
||||
self.spatial_transform = transforms.Compose([
|
||||
transforms.CenterCrop(resolution),
|
||||
])
|
||||
elif spatial_transform == "resize_center_crop":
|
||||
# assert(self.resolution[0] == self.resolution[1])
|
||||
self.spatial_transform = transforms.Compose([
|
||||
transforms.Resize(min(self.resolution)),
|
||||
transforms.CenterCrop(self.resolution),
|
||||
])
|
||||
elif spatial_transform == "resize":
|
||||
self.spatial_transform = transforms.Compose([
|
||||
transforms.Resize((self.resolution)),
|
||||
])
|
||||
else:
|
||||
raise NotImplementedError
|
||||
else:
|
||||
self.spatial_transform = None
|
||||
|
||||
def _load_metadata(self):
|
||||
metadata = pd.read_csv(self.meta_path)
|
||||
print('Loaded: ', len(metadata))
|
||||
|
||||
metadata['caption'] = metadata['name']
|
||||
del metadata['name']
|
||||
self.metadata = metadata
|
||||
self.metadata.dropna(inplace=True)
|
||||
|
||||
def _get_video_path(self, sample):
|
||||
full_video_fp = os.path.join(self.data_dir, sample['oripath'][1:] if sample['oripath'][0] == '/' else sample['oripath'])
|
||||
cond_full_video_fp = os.path.join(self.data_dir, sample['videopath'][1:] if sample['videopath'][0] == '/' else sample['videopath'])
|
||||
return full_video_fp, cond_full_video_fp
|
||||
|
||||
def __getitem__(self, index):
|
||||
##
|
||||
if self.random_fs:
|
||||
frame_stride = random.randint(self.frame_stride_min, self.frame_stride)
|
||||
else:
|
||||
frame_stride = self.frame_stride
|
||||
|
||||
## get frames until success
|
||||
while True:
|
||||
index = index % len(self.metadata)
|
||||
sample = self.metadata.iloc[index]
|
||||
video_path, cond_video_path = self._get_video_path(sample)
|
||||
#video_path = "/apdcephfs/share_1290939/0_public_datasets/WebVid/videos/002001_002050/1023214570.mp4"
|
||||
caption = sample['caption']
|
||||
frameid = int(sample['frameid'])
|
||||
try:
|
||||
if self.load_raw_resolution:
|
||||
video_reader = VideoReader(video_path, ctx=cpu(0))
|
||||
cond_video_reader = VideoReader(cond_video_path, ctx=cpu(0))
|
||||
else:
|
||||
NotImplementedError("Must use load_raw_resolution=True")
|
||||
|
||||
if len(video_reader) < self.video_length or len(cond_video_reader) < self.video_length:
|
||||
print(f"video length ({len(video_reader)}) or Cond video length ({len(cond_video_reader)}) is smaller than target length({self.video_length})")
|
||||
index += 1
|
||||
continue
|
||||
else:
|
||||
pass
|
||||
except:
|
||||
index += 1
|
||||
print(f"Load video failed! path = {video_path}")
|
||||
continue
|
||||
|
||||
frame_stride = 1
|
||||
|
||||
start_idx = 0
|
||||
|
||||
|
||||
frame_indices = [start_idx + frame_stride*i for i in range(self.video_length)]
|
||||
try:
|
||||
frames = video_reader.get_batch(frame_indices)
|
||||
frames_cond = cond_video_reader.get_batch(frame_indices)
|
||||
break
|
||||
except:
|
||||
print(f"Get frames failed! path = {video_path}")
|
||||
index += 1
|
||||
continue
|
||||
|
||||
## process data
|
||||
assert(frames.shape[0] == self.video_length),f'{len(frames)}, self.video_length={self.video_length}'
|
||||
assert(frames_cond.shape[0] == self.video_length),f'{len(frames_cond)}, self.video_length={self.video_length}'
|
||||
frames = torch.tensor(frames.asnumpy()).permute(3, 0, 1, 2).float() # [t,h,w,c] -> [c,t,h,w]
|
||||
frames_cond = torch.tensor(frames_cond.asnumpy()).permute(3, 0, 1, 2).float() # [t,h,w,c] -> [c,t,h,w]
|
||||
|
||||
|
||||
if self.spatial_transform is not None:
|
||||
frames = self.spatial_transform(frames)
|
||||
frames_cond = self.spatial_transform(frames_cond)
|
||||
|
||||
if self.resolution is not None:
|
||||
assert (frames.shape[2], frames.shape[3]) == (self.resolution[0], self.resolution[1]), f'frames={frames.shape}, self.resolution={self.resolution}'
|
||||
frames = (frames / 255 - 0.5) * 2
|
||||
frames_cond = (frames_cond / 255 - 0.5) * 2
|
||||
|
||||
frames_cond[:,frameid,:,:] = frames[:,frameid,:,:]
|
||||
data = {'video': frames, 'caption': caption, 'path': video_path, 'fps': 10, 'frame_stride': frame_stride, 'video_cond': frames_cond, 'frameid': frameid}
|
||||
return data
|
||||
|
||||
def __len__(self):
|
||||
return len(self.metadata)
|
||||
@@ -0,0 +1,23 @@
|
||||
from abc import abstractmethod
|
||||
from torch.utils.data import IterableDataset
|
||||
|
||||
|
||||
class Txt2ImgIterableBaseDataset(IterableDataset):
|
||||
'''
|
||||
Define an interface to make the IterableDatasets for text2img data chainable
|
||||
'''
|
||||
def __init__(self, num_records=0, valid_ids=None, size=256):
|
||||
super().__init__()
|
||||
self.num_records = num_records
|
||||
self.valid_ids = valid_ids
|
||||
self.sample_ids = valid_ids
|
||||
self.size = size
|
||||
|
||||
print(f'{self.__class__.__name__} dataset contains {self.__len__()} examples.')
|
||||
|
||||
def __len__(self):
|
||||
return self.num_records
|
||||
|
||||
@abstractmethod
|
||||
def __iter__(self):
|
||||
pass
|
||||
@@ -0,0 +1,202 @@
|
||||
import os
|
||||
import random
|
||||
from tqdm import tqdm
|
||||
import pandas as pd
|
||||
from decord import VideoReader, cpu
|
||||
|
||||
import torch
|
||||
from torch.utils.data import Dataset
|
||||
from torch.utils.data import DataLoader
|
||||
from torchvision import transforms
|
||||
|
||||
|
||||
class WebVid(Dataset):
|
||||
"""
|
||||
WebVid Dataset.
|
||||
Assumes webvid data is structured as follows.
|
||||
Webvid/
|
||||
videos/
|
||||
000001_000050/ ($page_dir)
|
||||
1.mp4 (videoid.mp4)
|
||||
...
|
||||
5000.mp4
|
||||
...
|
||||
"""
|
||||
def __init__(self,
|
||||
meta_path,
|
||||
data_dir,
|
||||
subsample=None,
|
||||
video_length=16,
|
||||
resolution=[256, 512],
|
||||
frame_stride=1,
|
||||
frame_stride_min=1,
|
||||
spatial_transform=None,
|
||||
crop_resolution=None,
|
||||
fps_max=None,
|
||||
load_raw_resolution=False,
|
||||
fixed_fps=None,
|
||||
random_fs=False,
|
||||
):
|
||||
self.meta_path = meta_path
|
||||
self.data_dir = data_dir
|
||||
self.subsample = subsample
|
||||
self.video_length = video_length
|
||||
self.resolution = [resolution, resolution] if isinstance(resolution, int) else resolution
|
||||
self.fps_max = fps_max
|
||||
self.frame_stride = frame_stride
|
||||
self.frame_stride_min = frame_stride_min
|
||||
self.fixed_fps = fixed_fps
|
||||
self.load_raw_resolution = load_raw_resolution
|
||||
self.random_fs = random_fs
|
||||
self._load_metadata()
|
||||
if spatial_transform is not None:
|
||||
if spatial_transform == "random_crop":
|
||||
self.spatial_transform = transforms.RandomCrop(crop_resolution)
|
||||
elif spatial_transform == "center_crop":
|
||||
self.spatial_transform = transforms.Compose([
|
||||
transforms.CenterCrop(resolution),
|
||||
])
|
||||
elif spatial_transform == "resize_center_crop":
|
||||
# assert(self.resolution[0] == self.resolution[1])
|
||||
self.spatial_transform = transforms.Compose([
|
||||
transforms.Resize(min(self.resolution)),
|
||||
transforms.CenterCrop(self.resolution),
|
||||
])
|
||||
elif spatial_transform == "resize":
|
||||
self.spatial_transform = transforms.Resize(self.resolution)
|
||||
else:
|
||||
raise NotImplementedError
|
||||
else:
|
||||
self.spatial_transform = None
|
||||
|
||||
def _load_metadata(self):
|
||||
metadata = pd.read_csv(self.meta_path)
|
||||
print(f'>>> {len(metadata)} data samples loaded.')
|
||||
if self.subsample is not None:
|
||||
metadata = metadata.sample(self.subsample, random_state=0)
|
||||
|
||||
metadata['caption'] = metadata['name']
|
||||
del metadata['name']
|
||||
self.metadata = metadata
|
||||
self.metadata.dropna(inplace=True)
|
||||
|
||||
def _get_video_path(self, sample):
|
||||
rel_video_fp = os.path.join(sample['page_dir'], str(sample['videoid']) + '.mp4')
|
||||
full_video_fp = os.path.join(self.data_dir, 'videos', rel_video_fp)
|
||||
return full_video_fp
|
||||
|
||||
def __getitem__(self, index):
|
||||
if self.random_fs:
|
||||
frame_stride = random.randint(self.frame_stride_min, self.frame_stride)
|
||||
else:
|
||||
frame_stride = self.frame_stride
|
||||
|
||||
## get frames until success
|
||||
while True:
|
||||
index = index % len(self.metadata)
|
||||
sample = self.metadata.iloc[index]
|
||||
video_path = self._get_video_path(sample)
|
||||
## video_path should be in the format of "....../WebVid/videos/$page_dir/$videoid.mp4"
|
||||
caption = sample['caption']
|
||||
|
||||
try:
|
||||
if self.load_raw_resolution:
|
||||
video_reader = VideoReader(video_path, ctx=cpu(0))
|
||||
else:
|
||||
video_reader = VideoReader(video_path, ctx=cpu(0), width=530, height=300)
|
||||
if len(video_reader) < self.video_length:
|
||||
print(f"video length ({len(video_reader)}) is smaller than target length({self.video_length})")
|
||||
index += 1
|
||||
continue
|
||||
else:
|
||||
pass
|
||||
except:
|
||||
index += 1
|
||||
print(f"Load video failed! path = {video_path}")
|
||||
continue
|
||||
|
||||
fps_ori = video_reader.get_avg_fps()
|
||||
if self.fixed_fps is not None:
|
||||
frame_stride = int(frame_stride * (1.0 * fps_ori / self.fixed_fps))
|
||||
|
||||
## to avoid extreme cases when fixed_fps is used
|
||||
frame_stride = max(frame_stride, 1)
|
||||
|
||||
## get valid range (adapting case by case)
|
||||
required_frame_num = frame_stride * (self.video_length-1) + 1
|
||||
frame_num = len(video_reader)
|
||||
if frame_num < required_frame_num:
|
||||
## drop extra samples if fixed fps is required
|
||||
if self.fixed_fps is not None and frame_num < required_frame_num * 0.5:
|
||||
index += 1
|
||||
continue
|
||||
else:
|
||||
frame_stride = frame_num // self.video_length
|
||||
required_frame_num = frame_stride * (self.video_length-1) + 1
|
||||
|
||||
## select a random clip
|
||||
random_range = frame_num - required_frame_num
|
||||
start_idx = random.randint(0, random_range) if random_range > 0 else 0
|
||||
|
||||
## calculate frame indices
|
||||
frame_indices = [start_idx + frame_stride*i for i in range(self.video_length)]
|
||||
try:
|
||||
frames = video_reader.get_batch(frame_indices)
|
||||
break
|
||||
except:
|
||||
print(f"Get frames failed! path = {video_path}; [max_ind vs frame_total:{max(frame_indices)} / {frame_num}]")
|
||||
index += 1
|
||||
continue
|
||||
|
||||
## process data
|
||||
assert(frames.shape[0] == self.video_length),f'{len(frames)}, self.video_length={self.video_length}'
|
||||
frames = torch.tensor(frames.asnumpy()).permute(3, 0, 1, 2).float() # [t,h,w,c] -> [c,t,h,w]
|
||||
|
||||
if self.spatial_transform is not None:
|
||||
frames = self.spatial_transform(frames)
|
||||
|
||||
if self.resolution is not None:
|
||||
assert (frames.shape[2], frames.shape[3]) == (self.resolution[0], self.resolution[1]), f'frames={frames.shape}, self.resolution={self.resolution}'
|
||||
|
||||
## turn frames tensors to [-1,1]
|
||||
frames = (frames / 255 - 0.5) * 2
|
||||
fps_clip = fps_ori // frame_stride
|
||||
if self.fps_max is not None and fps_clip > self.fps_max:
|
||||
fps_clip = self.fps_max
|
||||
|
||||
data = {'video': frames, 'caption': caption, 'path': video_path, 'fps': fps_clip, 'frame_stride': frame_stride}
|
||||
return data
|
||||
|
||||
def __len__(self):
|
||||
return len(self.metadata)
|
||||
|
||||
|
||||
if __name__== "__main__":
|
||||
meta_path = "" ## path to the meta file
|
||||
data_dir = "" ## path to the data directory
|
||||
save_dir = "" ## path to the save directory
|
||||
dataset = WebVid(meta_path,
|
||||
data_dir,
|
||||
subsample=None,
|
||||
video_length=16,
|
||||
resolution=[256,448],
|
||||
frame_stride=4,
|
||||
spatial_transform="resize_center_crop",
|
||||
crop_resolution=None,
|
||||
fps_max=None,
|
||||
load_raw_resolution=True
|
||||
)
|
||||
dataloader = DataLoader(dataset,
|
||||
batch_size=1,
|
||||
num_workers=0,
|
||||
shuffle=False)
|
||||
|
||||
|
||||
import sys
|
||||
sys.path.insert(1, os.path.join(sys.path[0], '..', '..'))
|
||||
from utils.save_video import tensor_to_mp4
|
||||
for i, batch in tqdm(enumerate(dataloader), desc="Data Batch"):
|
||||
video = batch['video']
|
||||
name = batch['path'][0].split('videos/')[-1].replace('/','_')
|
||||
tensor_to_mp4(video, save_dir+'/'+name, fps=8)
|
||||
|
||||
@@ -0,0 +1,95 @@
|
||||
import torch
|
||||
import numpy as np
|
||||
|
||||
|
||||
class AbstractDistribution:
|
||||
def sample(self):
|
||||
raise NotImplementedError()
|
||||
|
||||
def mode(self):
|
||||
raise NotImplementedError()
|
||||
|
||||
|
||||
class DiracDistribution(AbstractDistribution):
|
||||
def __init__(self, value):
|
||||
self.value = value
|
||||
|
||||
def sample(self):
|
||||
return self.value
|
||||
|
||||
def mode(self):
|
||||
return self.value
|
||||
|
||||
|
||||
class DiagonalGaussianDistribution(object):
|
||||
def __init__(self, parameters, deterministic=False):
|
||||
self.parameters = parameters
|
||||
self.mean, self.logvar = torch.chunk(parameters, 2, dim=1)
|
||||
self.logvar = torch.clamp(self.logvar, -30.0, 20.0)
|
||||
self.deterministic = deterministic
|
||||
self.std = torch.exp(0.5 * self.logvar)
|
||||
self.var = torch.exp(self.logvar)
|
||||
if self.deterministic:
|
||||
self.var = self.std = torch.zeros_like(self.mean).to(device=self.parameters.device)
|
||||
|
||||
def sample(self, noise=None):
|
||||
if noise is None:
|
||||
noise = torch.randn(self.mean.shape)
|
||||
|
||||
x = self.mean + self.std * noise.to(device=self.parameters.device)
|
||||
return x
|
||||
|
||||
def kl(self, other=None):
|
||||
if self.deterministic:
|
||||
return torch.Tensor([0.])
|
||||
else:
|
||||
if other is None:
|
||||
return 0.5 * torch.sum(torch.pow(self.mean, 2)
|
||||
+ self.var - 1.0 - self.logvar,
|
||||
dim=[1, 2, 3])
|
||||
else:
|
||||
return 0.5 * torch.sum(
|
||||
torch.pow(self.mean - other.mean, 2) / other.var
|
||||
+ self.var / other.var - 1.0 - self.logvar + other.logvar,
|
||||
dim=[1, 2, 3])
|
||||
|
||||
def nll(self, sample, dims=[1,2,3]):
|
||||
if self.deterministic:
|
||||
return torch.Tensor([0.])
|
||||
logtwopi = np.log(2.0 * np.pi)
|
||||
return 0.5 * torch.sum(
|
||||
logtwopi + self.logvar + torch.pow(sample - self.mean, 2) / self.var,
|
||||
dim=dims)
|
||||
|
||||
def mode(self):
|
||||
return self.mean
|
||||
|
||||
|
||||
def normal_kl(mean1, logvar1, mean2, logvar2):
|
||||
"""
|
||||
source: https://github.com/openai/guided-diffusion/blob/27c20a8fab9cb472df5d6bdd6c8d11c8f430b924/guided_diffusion/losses.py#L12
|
||||
Compute the KL divergence between two gaussians.
|
||||
Shapes are automatically broadcasted, so batches can be compared to
|
||||
scalars, among other use cases.
|
||||
"""
|
||||
tensor = None
|
||||
for obj in (mean1, logvar1, mean2, logvar2):
|
||||
if isinstance(obj, torch.Tensor):
|
||||
tensor = obj
|
||||
break
|
||||
assert tensor is not None, "at least one argument must be a Tensor"
|
||||
|
||||
# Force variances to be Tensors. Broadcasting helps convert scalars to
|
||||
# Tensors, but it does not work for torch.exp().
|
||||
logvar1, logvar2 = [
|
||||
x if isinstance(x, torch.Tensor) else torch.tensor(x).to(tensor)
|
||||
for x in (logvar1, logvar2)
|
||||
]
|
||||
|
||||
return 0.5 * (
|
||||
-1.0
|
||||
+ logvar2
|
||||
- logvar1
|
||||
+ torch.exp(logvar1 - logvar2)
|
||||
+ ((mean1 - mean2) ** 2) * torch.exp(-logvar2)
|
||||
)
|
||||
@@ -0,0 +1,76 @@
|
||||
import torch
|
||||
from torch import nn
|
||||
|
||||
|
||||
class LitEma(nn.Module):
|
||||
def __init__(self, model, decay=0.9999, use_num_upates=True):
|
||||
super().__init__()
|
||||
if decay < 0.0 or decay > 1.0:
|
||||
raise ValueError('Decay must be between 0 and 1')
|
||||
|
||||
self.m_name2s_name = {}
|
||||
self.register_buffer('decay', torch.tensor(decay, dtype=torch.float32))
|
||||
self.register_buffer('num_updates', torch.tensor(0,dtype=torch.int) if use_num_upates
|
||||
else torch.tensor(-1,dtype=torch.int))
|
||||
|
||||
for name, p in model.named_parameters():
|
||||
if p.requires_grad:
|
||||
#remove as '.'-character is not allowed in buffers
|
||||
s_name = name.replace('.','')
|
||||
self.m_name2s_name.update({name:s_name})
|
||||
self.register_buffer(s_name,p.clone().detach().data)
|
||||
|
||||
self.collected_params = []
|
||||
|
||||
def forward(self,model):
|
||||
decay = self.decay
|
||||
|
||||
if self.num_updates >= 0:
|
||||
self.num_updates += 1
|
||||
decay = min(self.decay,(1 + self.num_updates) / (10 + self.num_updates))
|
||||
|
||||
one_minus_decay = 1.0 - decay
|
||||
|
||||
with torch.no_grad():
|
||||
m_param = dict(model.named_parameters())
|
||||
shadow_params = dict(self.named_buffers())
|
||||
|
||||
for key in m_param:
|
||||
if m_param[key].requires_grad:
|
||||
sname = self.m_name2s_name[key]
|
||||
shadow_params[sname] = shadow_params[sname].type_as(m_param[key])
|
||||
shadow_params[sname].sub_(one_minus_decay * (shadow_params[sname] - m_param[key]))
|
||||
else:
|
||||
assert not key in self.m_name2s_name
|
||||
|
||||
def copy_to(self, model):
|
||||
m_param = dict(model.named_parameters())
|
||||
shadow_params = dict(self.named_buffers())
|
||||
for key in m_param:
|
||||
if m_param[key].requires_grad:
|
||||
m_param[key].data.copy_(shadow_params[self.m_name2s_name[key]].data)
|
||||
else:
|
||||
assert not key in self.m_name2s_name
|
||||
|
||||
def store(self, parameters):
|
||||
"""
|
||||
Save the current parameters for restoring later.
|
||||
Args:
|
||||
parameters: Iterable of `torch.nn.Parameter`; the parameters to be
|
||||
temporarily stored.
|
||||
"""
|
||||
self.collected_params = [param.clone() for param in parameters]
|
||||
|
||||
def restore(self, parameters):
|
||||
"""
|
||||
Restore the parameters stored with the `store` method.
|
||||
Useful to validate the model with EMA parameters without affecting the
|
||||
original optimization process. Store the parameters before the
|
||||
`copy_to` method. After validation (or model saving), use this to
|
||||
restore the former parameters.
|
||||
Args:
|
||||
parameters: Iterable of `torch.nn.Parameter`; the parameters to be
|
||||
updated with the stored parameters.
|
||||
"""
|
||||
for c_param, param in zip(self.collected_params, parameters):
|
||||
param.data.copy_(c_param.data)
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user