Update README.md
This commit is contained in:
 Extraltodeus
@@ -7,49 +7,6 @@ No more burns and 160% faster gens with the warp drive node.
|
||||
Now includes custom attention modifiers and interesting presets.
|
||||
|
||||
|
||||
## Last update (14.05.24):
|
||||
- fix the little mem leak 😀
|
||||
- temporarily disabled the timed SAG node because an update broke it.
|
||||
- added node: **preset loader**. Can do what the other can and much more like modify the attention mechanisms! Mostly tested on SDXL 😀!
|
||||
- Some presets are slower than others. Just like for the perturbed attention guidance for example. Most are just as fast.
|
||||
- About some of the presets:
|
||||
- For SD 1.5 "crossed conds customized 3" seems amazing!
|
||||
- "Enhanced_details_and_tweaked_attention" works better on creative generations and less on characters.
|
||||
- "Reinforced_style" does not regulates the CFG, gives MUCH MORE importance to your negative prompt, works with 12 steps and is slightly slower.
|
||||
- "The red riding latent" only works with SDXL. It is an almost nonsensical mix of attention tweaks. Best with 12 steps and really nice with creative prompts. Has the tendency to give more red clothings to the characters. Hence the name.
|
||||
- "Excellent_attention" is the default settings for the node described below. Don't delete it or the node won't work. 🙃
|
||||
- "Potato Attention Guidance" is really nice for portraits of happy people...
|
||||
- There are a bunch of others. I've generated examples which you can find in the example grids folder.
|
||||
- Most of these have been tested on SDXL. I have very little idea of the effect on SD 1.5
|
||||
- The presets are .json files and can contain a string which will go through eval(). ⚠
|
||||
- Always check what is inside before running it when it comes from someone else! I hesitated to share a preset which would plan a shutdown in 60 seconds named "actually shut down the computer in one minute" to let you be aware but that would bother more than it would be helfpul.
|
||||
- added node: "**Excellent attention**" developped by myself and based on this [astonishingly easy to understand research paper!](https://github.com/Extraltodeus/temp/blob/main/very_science.jpg) But in short:
|
||||
- Just try it. [Do it](https://www.youtube.com/watch?v=ZXsQAXx_ao0).
|
||||
- This node allows to disable the input layer 8 on self and cross attention.
|
||||
- But also to apply a custom modification on cross attention middle layer 0. The "patch_cond" and "patch_uncond" toggles are about this modification.
|
||||
- While the modification is definitely not very ressource costy, the light patch uses less VRAM.
|
||||
- The multiplier influences the cross attention and reinforces prompt-following. But like for real. Works better with the "light patch" toggle ON.
|
||||
- I have ~~only~~ mostly tested it with SDXL.
|
||||
- You can find a grid example of this node's settings in the "grids_example" folder.
|
||||
- For some reason the Juggernaut model does not work with it and I have no idea why.
|
||||
- Customizable attention modifiers:
|
||||
- Check the ["attention_modifiers_explainations"](https://github.com/Extraltodeus/ComfyUI-AutomaticCFG/blob/main/workflows/attention_modifiers_explainations.png) in the workflows. 👀 It is basically a tutorial.
|
||||
- Experiment what each layer really do by using what is basically a bruteforcing node! (the Attention modifiers tester node)
|
||||
- This is how you do a [Perturbed Attention Guidance](https://github.com/Extraltodeus/temp/blob/main/PAG.png) for example
|
||||
|
||||
<div align="center">
|
||||
|
||||
### 😊 [Gallery of generated images and workflows with this latest update HERE!](https://www.patreon.com/posts/104245818) 😊
|
||||
|
||||
</div>
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
<sub>12 steps in one shot / 4.2 seconds per image / using the "Excellent_attention" patch.</sub>
|
||||
|
||||
|
||||
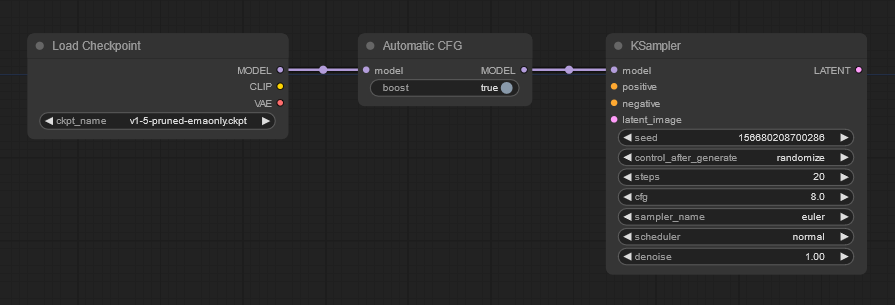
# Usage:
|
||||
|
||||
|
||||
@@ -140,6 +97,48 @@ Sample and Distribution Quality in Diffusion Models](https://arxiv.org/pdf/2404.
|
||||
- added the "Warp drive" node. It uses a new method of my own cooking which uses the previous step to determin a negative. Cutting the generation time by half for approx 3/4 of the steps.
|
||||
- added example workflows with 10-12 steps but of course you can do more steps if needed. It is not a goal to do less steps in general but also to show it is compatible.
|
||||
|
||||
## Last update (14.05.24):
|
||||
- fix the little mem leak 😀
|
||||
- temporarily disabled the timed SAG node because an update broke it.
|
||||
- added node: **preset loader**. Can do what the other can and much more like modify the attention mechanisms! Mostly tested on SDXL 😀!
|
||||
- Some presets are slower than others. Just like for the perturbed attention guidance for example. Most are just as fast.
|
||||
- About some of the presets:
|
||||
- For SD 1.5 "crossed conds customized 3" seems amazing!
|
||||
- "Enhanced_details_and_tweaked_attention" works better on creative generations and less on characters.
|
||||
- "Reinforced_style" does not regulates the CFG, gives MUCH MORE importance to your negative prompt, works with 12 steps and is slightly slower.
|
||||
- "The red riding latent" only works with SDXL. It is an almost nonsensical mix of attention tweaks. Best with 12 steps and really nice with creative prompts. Has the tendency to give more red clothings to the characters. Hence the name.
|
||||
- "Excellent_attention" is the default settings for the node described below. Don't delete it or the node won't work. 🙃
|
||||
- "Potato Attention Guidance" is really nice for portraits of happy people...
|
||||
- There are a bunch of others. I've generated examples which you can find in the example grids folder.
|
||||
- Most of these have been tested on SDXL. I have very little idea of the effect on SD 1.5
|
||||
- The presets are .json files and can contain a string which will go through eval(). ⚠
|
||||
- Always check what is inside before running it when it comes from someone else! I hesitated to share a preset which would plan a shutdown in 60 seconds named "actually shut down the computer in one minute" to let you be aware but that would bother more than it would be helfpul.
|
||||
- added node: "**Excellent attention**" developped by myself and based on this [astonishingly easy to understand research paper!](https://github.com/Extraltodeus/temp/blob/main/very_science.jpg) But in short:
|
||||
- Just try it. [Do it](https://www.youtube.com/watch?v=ZXsQAXx_ao0).
|
||||
- This node allows to disable the input layer 8 on self and cross attention.
|
||||
- But also to apply a custom modification on cross attention middle layer 0. The "patch_cond" and "patch_uncond" toggles are about this modification.
|
||||
- While the modification is definitely not very ressource costy, the light patch uses less VRAM.
|
||||
- The multiplier influences the cross attention and reinforces prompt-following. But like for real. Works better with the "light patch" toggle ON.
|
||||
- I have ~~only~~ mostly tested it with SDXL.
|
||||
- You can find a grid example of this node's settings in the "grids_example" folder.
|
||||
- For some reason the Juggernaut model does not work with it and I have no idea why.
|
||||
- Customizable attention modifiers:
|
||||
- Check the ["attention_modifiers_explainations"](https://github.com/Extraltodeus/ComfyUI-AutomaticCFG/blob/main/workflows/attention_modifiers_explainations.png) in the workflows. 👀 It is basically a tutorial.
|
||||
- Experiment what each layer really do by using what is basically a bruteforcing node! (the Attention modifiers tester node)
|
||||
- This is how you do a [Perturbed Attention Guidance](https://github.com/Extraltodeus/temp/blob/main/PAG.png) for example
|
||||
|
||||
<div align="center">
|
||||
|
||||
### 😊 [Gallery of generated images and workflows with this latest update HERE!](https://www.patreon.com/posts/104245818) 😊
|
||||
|
||||
</div>
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
<sub>12 steps in one shot / 4.2 seconds per image / using the "Excellent_attention" patch.</sub>
|
||||
|
||||
# 10 steps with only 2 having the negative enabled. So ~170% faster. 2.5 seconds on a RTX4070
|
||||
|
||||

|
||||
|
||||
Reference in New Issue
Block a user