
95 lines
5.7 KiB
Markdown
95 lines
5.7 KiB
Markdown
My own version "from scratch" of a self-rescaling CFG. It ain't much but it's honest work.
|
|
|
|
Updated:
|
|
- Up to 28.5% faster generation speed than normal
|
|
- Negative weighting
|
|
|
|
05.04.24:
|
|
|
|
- Updated to latest ComfyUI version. If you get an error: update your ComfyUI
|
|
|
|
15.04.24
|
|
|
|
- Added "no uncond" node which completely disable the negative and doubles the speed while rescaling the latent space in the post-cfg function up until the sigmas are at 1 (or really, 6.86%). By itself it is not perfect and I'm searching for solutions to improve the final result. It seems to work better with dpmpp3m_sde/exponential if you're not using anything else. If you are using the PAG node then you don't need to care about the sampler but will generate at a normal speed. Result will be simply different (I personally like them).
|
|
- To use the [PAG node](https://github.com/pamparamm/sd-perturbed-attention/tree/master) without the complete slow-down (if using the no-uncond node) or at least take advantage of the boost feature:
|
|
- in the "pag_nodes.py" file look for "disable_cfg1_optimization=True"
|
|
- set it to "disable_cfg1_optimization=False".
|
|
- For the negative lerp function in the other nodes the scale has been divided by two. So if you were using it at 10, set it to 5.
|
|
|
|
# In short:
|
|
|
|
Quality > prompt following (but somehow it also feels like it follows the prompt more so... I'll let you decide)
|
|
|
|
# Usage:
|
|
|
|
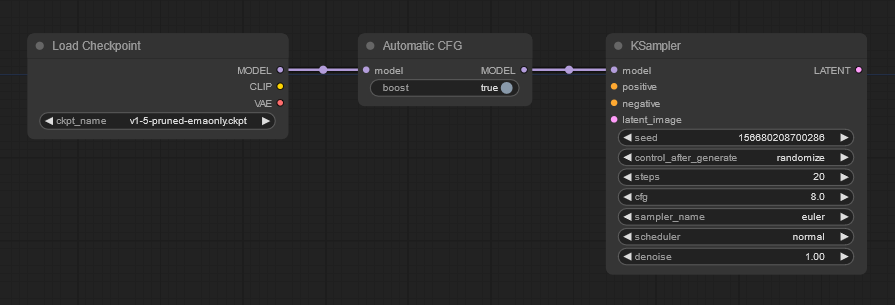
Normal node:
|
|
|
|
|
|
|
|
Negative strength version:
|
|
|
|

|
|
|
|
No uncond:
|
|
|
|

|
|
|
|
|
|
|
|
### That's it!
|
|
|
|
- The "boost" toggle will turn off the negative guidance when the sigmas are near 1. This doubles the inference speed. **To unpatch the function you have to start a batch with the toggle off.** Removing/disconnecting the node will not do it.
|
|
- The negative strength lerp the cond and uncond. Now in normal times the way I do this would burn things to the ground. But since it is initialy an anti-burn it just works. This idea is inspired by the [negative prompt weight](https://github.com/muerrilla/stable-diffusion-NPW) repository.
|
|
- I leave the advanced node for those who are interested. It will not be beneficial to those who do not feel like experimenting.
|
|
|
|
For 100 steps this is where the sigma are reaching 1:
|
|
|
|

|
|
|
|
There seem to be a slight improvement in quality when using the boost with my other node [CLIP Vector Sculptor text encode](https://github.com/Extraltodeus/Vector_Sculptor_ComfyUI) using the "mean" normalization option.
|
|
|
|
# Negative prompt x10 works like a charm (+speed boost)
|
|
|
|

|
|
|
|
# Just a note:
|
|
|
|
Your CFG won't be your CFG anymore. It is turned into a way to guide the CFG/final intensity/brightness/saturation. So don't hesitate to change your habits while trying!
|
|
|
|
# The rest of the explaination:
|
|
|
|
While this node is connected, this will turn your sampler's CFG scale into something else.
|
|
This methods works by rescaling the CFG at each step by evaluating the potential average min/max values. Aiming at a desired output intensity (by intensity I mean overall brightness/saturation/sharpness).
|
|
The base intensity has been arbitrarily chosen by me and your sampler's CFG scale will make this target vary.
|
|
I have set the "central" CFG at 8. Meaning that at 4 you will aim at half of the desired range while at 16 it will be doubled. This makes it feel slightly like the usual when you're around the normal values.
|
|
|
|
The CFG behavior during the sampling being automatically set for each channel makes it behave differently and therefores gives different outputs than the usual.
|
|
From my observations by printing the results while testing, it seems to be going from around 16 at the beginning, to something like 4 near the middle and ends up near ~7.
|
|
These values might have changed since I've done a thousand tests with different ways but that's to give you an idea, it's just me eyeballing the CLI's output.
|
|
|
|
I use the upper and lower 25% topk mean value as a reference to have some margin of manoeuver.
|
|
|
|
It makes the sampling generate overall better quality images. I get much less if not any artifacts anymore and my more creative prompts also tends to give more random, in a good way, different results.
|
|
|
|
I attribute this more random yet positive behavior to the fact that it seems to be starting high and then since it becomes lower, it self-corrects and improvise, taking advantage of the sampling process a lot more.
|
|
|
|
It is dead simple to use and made sampling more fun from my perspective :)
|
|
|
|
You will find it in the model_patches category.
|
|
|
|
TLDR: set your CFG at 8 to try it. No burned images and artifacts anymore. CFG is also a bit more sensitive because it's a proportion around 8.
|
|
|
|
Low scale like 4 also gives really nice results since your CFG is not the CFG anymore.
|
|
|
|
|
|
Also in general even with relatively low settings it seems to improve the quality.
|
|
|
|
It really helps to make the little detail fall into place:
|
|
|
|

|
|
|
|
|
|
Here too even with low settings, 14 steps/dpmpp2/karras/pseudo CFG at 6.5 on a normal SDXL model:
|
|

|
|
|