refactor: overhaul LLM toolkit architecture and standardize observability
- Core Refactoring: Migrated OpenAICompatibleLoader to a structured class design (ProviderRegistry, MessageBuilder, TokenEstimator) for enhanced maintainability.
- AsyncIO Fix: Resolved 'Event loop is closed' RuntimeError by transitioning to asyncio.run() for robust event loop lifecycle management within ComfyUI's threaded environment.
- Node Enhancements:
    - Added 'seed' parameter for deterministic cache invalidation control.
    - Fixed silent drop of system_prompt in stateless mode (enable_memory=False).
    - Refined category hierarchy: [Generate, Loader, Image] under a unified toolkit brand.
- Observability: Implemented project-wide geek-style logging with [LLMs_Toolkit] branding, execution latency tracking, and high-density token reporting.
- Cleanup: Removed legacy DeepSeek local model vertical, dependencies, and redundant utility nodes.
- Documentation: Simplified README and updated .gitignore for developer hygiene.
This commit is contained in:
 科林_Cyril Pilgrim
@@ -31,3 +31,6 @@ ENV/
|
||||
# OS
|
||||
.DS_Store
|
||||
Thumbs.db
|
||||
|
||||
# Tests
|
||||
tests/
|
||||
|
||||
Binary file not shown.
-241
@@ -1,241 +0,0 @@
|
||||
<div align="center">
|
||||
|
||||
# 🚀 ComfyUI-DeepSeek-Toolkit
|
||||
|
||||
**为ComfyUI工作流程注入强大的大语言模型力量!**
|
||||
|
||||
[](https://github.com/HuangYuChuh/ComfyUI-DeepSeek-Toolkit/stargazers)
|
||||
[](https://github.com/HuangYuChuh/ComfyUI-DeepSeek-Toolkit/network)
|
||||
[](https://github.com/HuangYuChuh/ComfyUI-DeepSeek-Toolkit/blob/main/LICENSE)
|
||||
[](https://www.python.org/)
|
||||
|
||||
**一个集成中国领先大语言模型的ComfyUI自定义节点套件**
|
||||
|
||||
</div>
|
||||
|
||||
---
|
||||
|
||||
## 📖 项目介绍
|
||||
|
||||
ComfyUI-DeepSeek-Toolkit 是一个专为ComfyUI设计的自定义节点包,致力于将中国最优秀的大语言模型(如DeepSeek、通义千问等)无缝集成到您的AI工作流程中。通过轻量级的API驱动方案,即使是计算资源有限的用户也能轻松体验到前沿AI技术的强大能力。
|
||||
|
||||
### 🎯 项目愿景
|
||||
|
||||
> **让AI技术惠及每一个创作者**
|
||||
>
|
||||
> 我们相信AI应该是赋能工具,而非不平等的根源。通过提供易于访问的解决方案,我们致力于让AI成为一种更具包容性和公平性的技术。
|
||||
|
||||
---
|
||||
|
||||
## ✨ 核心特性
|
||||
|
||||
### 🤖 支持的大语言模型
|
||||
|
||||
| 模型提供商 | 模型名称 | 特色功能 |
|
||||
|-----------|---------|---------|
|
||||
| 🔥 **DeepSeek** | DeepSeek-V2/V3 | 超强推理能力,代码生成专家 |
|
||||
| 🌟 **通义千问** | Qwen-Max/Plus | 多模态理解,中文优化 |
|
||||
| 🚀 **豆包** | Doubao-Pro | 对话生成,创意写作 |
|
||||
| ⚡ **星火** | Spark-Max | 语言理解,文本分析 |
|
||||
| 🧠 **智谱清言** | GLM-4 | 知识问答,逻辑推理 |
|
||||
| 🌙 **月之暗面** | Moonshot-V1 | 长文本处理,上下文理解 |
|
||||
| 🌊 **百川** | Baichuan-Turbo | 快速响应,高效处理 |
|
||||
| 🎭 **MiniMax** | ABAB-6.5 | 角色扮演,创意生成 |
|
||||
| 🔮 **阶跃星辰** | Step-1X | 多任务处理,智能推理 |
|
||||
|
||||
### 🛠️ 功能模块
|
||||
|
||||
<div align="center">
|
||||
|
||||
| 模块名称 | 功能描述 | 适用场景 |
|
||||
|---------|---------|----------|
|
||||
| 🔧 **LLM加载器** | 配置和加载不同的大语言模型 | 模型切换、参数调优 |
|
||||
| 🎨 **图像生成** | 基于文本描述生成高质量图像 | 创意设计、内容创作 |
|
||||
| 👁️ **图像理解** | 智能分析和描述图像内容 | 图像标注、内容审核 |
|
||||
| 📦 **模型管理** | 统一管理各种AI模型资源 | 模型版本控制、资源优化 |
|
||||
| 🔌 **OpenAI兼容** | 支持OpenAI格式的API调用 | 兼容性扩展、迁移便利 |
|
||||
| 🖼️ **图像预处理** | 智能优化图像质量和格式 | 数据清洗、格式转换 |
|
||||
|
||||
</div>
|
||||
|
||||
---
|
||||
|
||||
## 🚀 快速开始
|
||||
|
||||
### 📋 环境要求
|
||||
|
||||
- **Python**: 3.8 或更高版本
|
||||
- **ComfyUI**: 最新稳定版本
|
||||
- **操作系统**: Windows / macOS / Linux
|
||||
|
||||
### 🔧 安装指南
|
||||
|
||||
#### 方法一:通过ComfyUI Manager安装(推荐)
|
||||
|
||||
1. 在ComfyUI中打开 **Manager** 面板
|
||||
2. 搜索 \`ComfyUI-DeepSeek-Toolkit\`
|
||||
3. 点击 **安装** 并重启ComfyUI
|
||||
|
||||
#### 方法二:手动安装
|
||||
|
||||
\`\`\`bash
|
||||
# 进入ComfyUI的custom_nodes目录
|
||||
cd ComfyUI/custom_nodes/
|
||||
|
||||
# 克隆项目
|
||||
git clone https://github.com/HuangYuChuh/ComfyUI-DeepSeek-Toolkit.git
|
||||
|
||||
# 进入项目目录
|
||||
cd ComfyUI-DeepSeek-Toolkit
|
||||
|
||||
# 安装依赖
|
||||
pip install -r requirements.txt
|
||||
\`\`\`
|
||||
|
||||
### 🔑 API密钥配置
|
||||
|
||||
在使用前,您需要获取相应模型的API密钥:
|
||||
|
||||
1. **DeepSeek**: [获取API密钥](https://platform.deepseek.com/)
|
||||
2. **通义千问**: [获取API密钥](https://dashscope.aliyun.com/)
|
||||
3. **其他模型**: 请参考 [LLM API调用指南](./LLM%20API%20调用指南(中国版).md)
|
||||
|
||||
---
|
||||
|
||||
## 📚 使用指南
|
||||
|
||||
### 🎯 基础工作流程
|
||||
|
||||
1. **加载LLM节点**
|
||||
- 在ComfyUI中添加 \`DeepSeek LLM Loader\` 节点
|
||||
- 配置API密钥和模型参数
|
||||
|
||||
2. **连接功能节点**
|
||||
- 根据需求添加图像生成/理解节点
|
||||
- 配置输入输出连接
|
||||
|
||||
3. **运行工作流程**
|
||||
- 设置提示词和参数
|
||||
- 执行并查看结果
|
||||
|
||||
---
|
||||
|
||||
## 🛠️ 技术架构
|
||||
|
||||
### 📦 依赖项
|
||||
|
||||
\`\`\`txt
|
||||
torch>=1.9.0
|
||||
numpy>=1.21.0
|
||||
Pillow>=8.3.0
|
||||
aiohttp>=3.8.0
|
||||
transformers>=4.20.0
|
||||
git+https://github.com/deepseek-ai/Janus.git
|
||||
\`\`\`
|
||||
|
||||
### 🏗️ 项目结构
|
||||
|
||||
\`\`\`
|
||||
ComfyUI-DeepSeek-Toolkit/
|
||||
├── 📁 py/ # 核心模块目录
|
||||
│ ├── 🔧 llm_loader.py # LLM加载器
|
||||
│ ├── 🎨 image_generation.py # 图像生成模块
|
||||
│ ├── 👁️ image_understanding.py # 图像理解模块
|
||||
│ ├── 📦 model_loader.py # 模型管理器
|
||||
│ ├── 🔌 openai_compatible_loader.py # OpenAI兼容层
|
||||
│ └── 🖼️ image_preprocessor.py # 图像预处理器
|
||||
├── 📄 __init__.py # 主入口文件
|
||||
├── 📋 requirements.txt # 依赖列表
|
||||
├── 📖 README.md # 项目文档
|
||||
├── 📘 readme_en.md # 英文文档
|
||||
├── 📙 LLM API 调用指南(中国版).md # API调用指南
|
||||
└── 📜 LICENSE # 开源协议
|
||||
\`\`\`
|
||||
|
||||
---
|
||||
|
||||
## 🤝 贡献指南
|
||||
|
||||
我们欢迎所有形式的贡献!
|
||||
|
||||
### 🐛 报告问题
|
||||
|
||||
如果您发现了bug或有功能建议:
|
||||
|
||||
1. 在 [Issues](https://github.com/HuangYuChuh/ComfyUI-DeepSeek-Toolkit/issues) 中搜索相似问题
|
||||
2. 如果没有找到,请创建新的issue
|
||||
3. 请提供详细的描述和复现步骤
|
||||
|
||||
### 💡 提交代码
|
||||
|
||||
1. Fork本项目
|
||||
2. 创建功能分支 (\`git checkout -b feature/AmazingFeature\`)
|
||||
3. 提交更改 (\`git commit -m 'Add some AmazingFeature'\`)
|
||||
4. 推送到分支 (\`git push origin feature/AmazingFeature\`)
|
||||
5. 创建Pull Request
|
||||
|
||||
---
|
||||
|
||||
## 📈 发展路线图
|
||||
|
||||
### 🎯 近期计划
|
||||
|
||||
- [ ] 🚀 **v1.1.0**
|
||||
- [ ] 支持更多视频理解模型
|
||||
- [ ] 增加批处理功能
|
||||
- [ ] 优化内存使用
|
||||
|
||||
- [ ] 🌟 **v1.2.0**
|
||||
- [ ] 集成更多中国AI模型
|
||||
- [ ] 添加模型微调功能
|
||||
- [ ] 提供预构建工作流模板
|
||||
|
||||
### 🔮 长期规划
|
||||
|
||||
- 🧠 **智能化升级**: 自适应模型选择和参数优化
|
||||
- 🌐 **生态扩展**: 与更多AI平台和工具集成
|
||||
- 📊 **性能监控**: 实时性能分析和优化建议
|
||||
- 🎓 **教育资源**: 完善的教程和案例库
|
||||
|
||||
---
|
||||
|
||||
## 📞 支持与反馈
|
||||
|
||||
### 💬 社区交流
|
||||
|
||||
- **GitHub Issues**: [问题反馈](https://github.com/HuangYuChuh/ComfyUI-DeepSeek-Toolkit/issues)
|
||||
- **GitHub Discussions**: [社区讨论](https://github.com/HuangYuChuh/ComfyUI-DeepSeek-Toolkit/discussions)
|
||||
|
||||
### 📧 联系方式
|
||||
|
||||
如有商务合作或其他询问,请通过以下方式联系:
|
||||
|
||||
- **项目维护者**: [@HuangYuChuh](https://github.com/HuangYuChuh)
|
||||
- **项目主页**: [ComfyUI-DeepSeek-Toolkit](https://github.com/HuangYuChuh/ComfyUI-DeepSeek-Toolkit)
|
||||
|
||||
---
|
||||
|
||||
## 📄 开源协议
|
||||
|
||||
本项目采用 [GPL-2.0 License](https://github.com/HuangYuChuh/ComfyUI-DeepSeek-Toolkit/blob/main/LICENSE) 开源协议。
|
||||
|
||||
---
|
||||
|
||||
## 🙏 致谢
|
||||
|
||||
感谢以下项目和社区的支持:
|
||||
|
||||
- 🎨 [ComfyUI](https://github.com/comfyanonymous/ComfyUI) - 强大的AI工作流平台
|
||||
- 🤖 [DeepSeek](https://www.deepseek.com/) - 优秀的大语言模型
|
||||
- 🌟 [阿里云通义千问](https://tongyi.aliyun.com/) - 多模态AI助手
|
||||
- 👥 所有贡献者和用户的支持与反馈
|
||||
|
||||
---
|
||||
|
||||
<div align="center">
|
||||
|
||||
**⭐ 如果这个项目对您有帮助,请给我们一个Star!**
|
||||
|
||||
[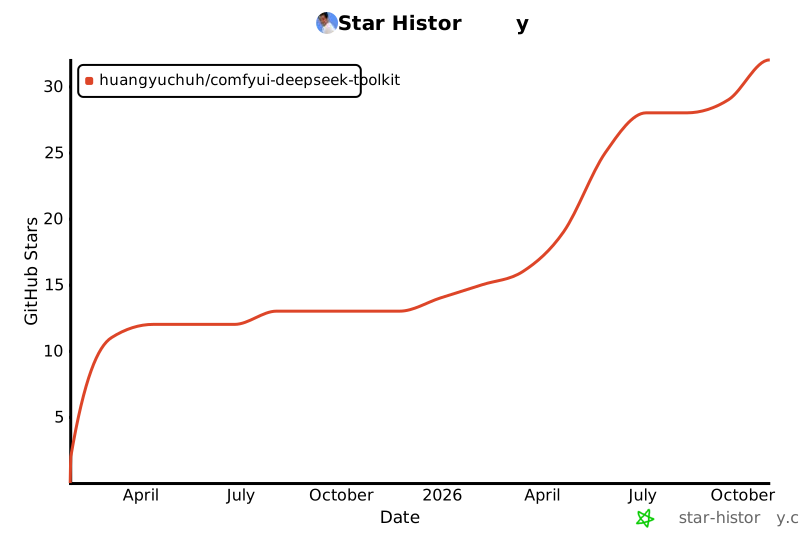](https://star-history.com/#HuangYuChuh/ComfyUI-DeepSeek-Toolkit&Date)
|
||||
|
||||
</div>
|
||||
@@ -1 +0,0 @@
|
||||
# Jupyter示例将在这里提供
|
||||
@@ -1 +0,0 @@
|
||||
# 示例工作流将在这里提供
|
||||
+372
-239
@@ -1,21 +1,175 @@
|
||||
import comfy
|
||||
import folder_paths
|
||||
import nodes
|
||||
import aiohttp
|
||||
import json
|
||||
import asyncio
|
||||
import time
|
||||
import random
|
||||
from typing import Optional, List, Dict, Tuple, Any
|
||||
from dataclasses import dataclass
|
||||
from aiohttp import ClientSession, ClientError
|
||||
from typing import Optional, List, Dict
|
||||
import time # 添加时间模块
|
||||
import random # 添加随机数模块
|
||||
import torch
|
||||
|
||||
|
||||
@dataclass
|
||||
class ProviderConfig:
|
||||
"""LLM provider endpoint configuration"""
|
||||
name: str
|
||||
base_url: str
|
||||
requires_string_content: bool = False
|
||||
|
||||
|
||||
class ProviderRegistry:
|
||||
"""Centralized registry for LLM API providers"""
|
||||
|
||||
PROVIDERS = {
|
||||
"Qwen/通义千问": ProviderConfig(
|
||||
"Qwen",
|
||||
"https://dashscope.aliyuncs.com/compatible-mode/v1"
|
||||
),
|
||||
"DeepSeek/深度求索": ProviderConfig(
|
||||
"DeepSeek",
|
||||
"https://api.deepseek.com/v1/"
|
||||
),
|
||||
"DouBao/豆包": ProviderConfig(
|
||||
"DouBao",
|
||||
"https://ark.cn-beijing.volces.com/api/v3/"
|
||||
),
|
||||
"Spark/星火": ProviderConfig(
|
||||
"Spark",
|
||||
"https://spark-api-open.xf-yun.com/v1/",
|
||||
requires_string_content=True
|
||||
),
|
||||
"GLM/智谱清言": ProviderConfig(
|
||||
"GLM",
|
||||
"https://open.bigmodel.cn/api/paas/v4/"
|
||||
),
|
||||
"Moonshot/月之暗面": ProviderConfig(
|
||||
"Moonshot",
|
||||
"https://api.moonshot.cn/v1"
|
||||
),
|
||||
"Baichuan/百川": ProviderConfig(
|
||||
"Baichuan",
|
||||
"https://api.baichuan-ai.com/v1/",
|
||||
requires_string_content=True
|
||||
),
|
||||
"MiniMax/MiniMax": ProviderConfig(
|
||||
"MiniMax",
|
||||
"https://api.minimax.chat/v1/"
|
||||
),
|
||||
"StepFun/阶跃星辰": ProviderConfig(
|
||||
"StepFun",
|
||||
"https://api.stepfun.com/v1/"
|
||||
),
|
||||
"SenseChat/日日新": ProviderConfig(
|
||||
"SenseChat",
|
||||
"https://api.sensenova.cn/compatible-mode/v1",
|
||||
requires_string_content=True
|
||||
),
|
||||
}
|
||||
|
||||
@classmethod
|
||||
def get_provider(cls, provider_key: str) -> ProviderConfig:
|
||||
"""Get provider config or treat key as custom URL"""
|
||||
return cls.PROVIDERS.get(provider_key.strip(),
|
||||
ProviderConfig("Custom", provider_key.strip()))
|
||||
|
||||
|
||||
class MessageBuilder:
|
||||
"""Builds chat messages with support for multimodal content"""
|
||||
|
||||
@staticmethod
|
||||
def build_content(prompt: str, image_url: Optional[str] = None) -> List[Dict[str, Any]]:
|
||||
"""Build content array for user message"""
|
||||
content = []
|
||||
|
||||
if image_url:
|
||||
if not image_url.startswith("data:image"):
|
||||
raise ValueError("Image must be a valid base64 data URL")
|
||||
content.append({
|
||||
"type": "image_url",
|
||||
"image_url": {"url": image_url}
|
||||
})
|
||||
|
||||
if prompt.strip():
|
||||
content.append({
|
||||
"type": "text",
|
||||
"text": prompt
|
||||
})
|
||||
|
||||
if not content:
|
||||
raise ValueError("Content cannot be empty")
|
||||
|
||||
return content
|
||||
|
||||
@staticmethod
|
||||
def build_messages(
|
||||
content: List[Dict[str, Any]],
|
||||
system_prompt: Optional[str] = None
|
||||
) -> List[Dict[str, Any]]:
|
||||
"""Build complete message array"""
|
||||
messages = []
|
||||
|
||||
if system_prompt:
|
||||
messages.append({
|
||||
"role": "system",
|
||||
"content": system_prompt
|
||||
})
|
||||
|
||||
messages.append({
|
||||
"role": "user",
|
||||
"content": content
|
||||
})
|
||||
|
||||
return messages
|
||||
|
||||
@staticmethod
|
||||
def adapt_for_provider(
|
||||
messages: List[Dict[str, Any]],
|
||||
provider: ProviderConfig,
|
||||
prompt: str
|
||||
) -> List[Dict[str, Any]]:
|
||||
"""Adapt messages for provider-specific requirements"""
|
||||
if provider.requires_string_content:
|
||||
# Some providers require string content, not structured arrays
|
||||
adapted = []
|
||||
for msg in messages:
|
||||
if msg["role"] == "system":
|
||||
adapted.append(msg)
|
||||
elif msg["role"] == "user":
|
||||
adapted.append({
|
||||
"role": "user",
|
||||
"content": prompt if isinstance(prompt, str) else prompt
|
||||
})
|
||||
return adapted
|
||||
return messages
|
||||
|
||||
|
||||
class TokenEstimator:
|
||||
"""Estimates token usage for billing/logging purposes"""
|
||||
|
||||
@staticmethod
|
||||
def estimate_input_tokens(
|
||||
prompt: str,
|
||||
system_prompt: Optional[str] = None,
|
||||
image_url: Optional[str] = None
|
||||
) -> int:
|
||||
"""Simple character-based token estimation"""
|
||||
tokens = len(prompt)
|
||||
|
||||
if system_prompt:
|
||||
tokens += len(system_prompt)
|
||||
|
||||
if image_url:
|
||||
# Rough estimate: base64 image ~= length/1000 tokens
|
||||
tokens += len(image_url) // 1000
|
||||
|
||||
return tokens
|
||||
|
||||
|
||||
class OpenAICompatibleLoader:
|
||||
"""
|
||||
Custom node for OpenAI compatible API integration
|
||||
OpenAI-compatible API adapter for ComfyUI
|
||||
|
||||
Supports multiple LLM providers with unified interface.
|
||||
Designed for extensibility and clean architecture.
|
||||
"""
|
||||
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
@@ -29,251 +183,230 @@ class OpenAICompatibleLoader:
|
||||
},
|
||||
"optional": {
|
||||
"prep_img": ("STRING", {"default": "", "forceInput": True}),
|
||||
"system_prompt": ("STRING", {"default": "你是一个AI大模型", "multiline": True}),
|
||||
"system_prompt": ("STRING", {
|
||||
"default": "你是一个AI大模型",
|
||||
"multiline": True
|
||||
}),
|
||||
"prompt": ("STRING", {"multiline": True}),
|
||||
"temperature": ("FLOAT", {"default": 0.7, "min": 0.0, "max": 2.0}),
|
||||
"max_tokens": ("INT", {"default": 512, "min": 1, "max": 4096}),
|
||||
"enable_memory": ("BOOLEAN", {"default": False, "label": "Enable Memory"}),
|
||||
"temperature": ("FLOAT", {
|
||||
"default": 0.7,
|
||||
"min": 0.0,
|
||||
"max": 2.0
|
||||
}),
|
||||
"max_tokens": ("INT", {
|
||||
"default": 512,
|
||||
"min": 1,
|
||||
"max": 4096
|
||||
}),
|
||||
"enable_memory": ("BOOLEAN", {
|
||||
"default": False,
|
||||
"label": "Enable Memory"
|
||||
}),
|
||||
"seed": ("INT", {
|
||||
"default": 0,
|
||||
"min": 0,
|
||||
"max": 0xffffffffffffffff
|
||||
}),
|
||||
"api_key": ("STRING", {"default": ""})
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
RETURN_TYPES = ("STRING", "INT", "INT")
|
||||
RETURN_NAMES = ("text", "input_tokens", "output_tokens")
|
||||
FUNCTION = "generate"
|
||||
CATEGORY = "🚦ComfyUI_LLMs_Toolkit"
|
||||
|
||||
async def async_generate(self, payload: dict, actual_base_url: str, api_key: str):
|
||||
try:
|
||||
async with ClientSession() as session:
|
||||
try:
|
||||
async with session.post(
|
||||
f"{actual_base_url}/chat/completions",
|
||||
headers={
|
||||
"Content-Type": "application/json",
|
||||
"Authorization": f"Bearer {api_key}"
|
||||
},
|
||||
json=payload
|
||||
) as response:
|
||||
# 打印完整的请求内容以便调试
|
||||
# Simplified debug log
|
||||
print(f"[DEBUG] Request sent to model: {payload['model']}, temp: {payload['temperature']}, max_tokens: {payload['max_tokens']}")
|
||||
response.raise_for_status()
|
||||
data = await response.json()
|
||||
# 移除冗长的API响应日志
|
||||
response_content = data['choices'][0]['message']['content']
|
||||
# 简化后的响应内容日志
|
||||
print(f"Output: {response_content[:50]}...") # 只保留前50个字符
|
||||
return [response_content, data] # 返回值包括 response_content 和 data
|
||||
except Exception as e:
|
||||
print(f"[ERROR] 请求失败: {str(e)}") # 打印错误信息
|
||||
raise
|
||||
except ClientError as e:
|
||||
raise Exception(f"API request failed: {str(e)}")
|
||||
|
||||
def generate(self, base_url: str, api_key: str, prompt: str,
|
||||
model: str, temperature: float,
|
||||
max_tokens: int, system_prompt: Optional[str] = None, prep_img: Optional[str] = None, enable_memory: bool = False, seed: Optional[int] = None):
|
||||
|
||||
content = [] # 初始化内容列表
|
||||
|
||||
# 移除图像参数类型的日志
|
||||
|
||||
if prep_img:
|
||||
# 打印 prep_img 调试信息
|
||||
print(f"[DEBUG] Received prep_img: {prep_img[:50]}...") # 只保留前50个字符
|
||||
# 验证 prep_img 是否为有效的 base64 编码字符串
|
||||
if not prep_img.startswith("data:image"):
|
||||
raise ValueError("Processed image must be a valid base64 encoded string")
|
||||
|
||||
# 将 prep_img 添加到 content 中
|
||||
content.append({"type": "image_url", "image_url": {"url": prep_img}})
|
||||
|
||||
|
||||
|
||||
if prompt.strip():
|
||||
content.append({"type": "text", "text": prompt})
|
||||
|
||||
messages = [] # 初始化 messages 列表
|
||||
if system_prompt:
|
||||
messages.append({
|
||||
"role": "system",
|
||||
"content": system_prompt
|
||||
})
|
||||
|
||||
if content: # 只有当 content 列表不为空时才添加到 messages
|
||||
messages.append({
|
||||
"role": "user",
|
||||
"content": content
|
||||
})
|
||||
# 移除带有图像内容的消息日志
|
||||
elif not prompt.strip() and not system_prompt and prep_img is None:
|
||||
raise ValueError("用户输入的 prompt 不能为空")
|
||||
|
||||
# 模型选择逻辑 (保持不变)
|
||||
selected_model = model if model else "glm-4" # 默认模型为 glm-4
|
||||
print(f"[INFO] 使用模型: {selected_model}")
|
||||
|
||||
# base_url 映射表 (保持不变)
|
||||
base_url_mapping = {
|
||||
"Qwen/通义千问": "https://dashscope.aliyuncs.com/compatible-mode/v1",
|
||||
"DeepSeek/深度求索": "https://api.deepseek.com/v1/",
|
||||
"DouBao/豆包": "https://ark.cn-beijing.volces.com/api/v3/",
|
||||
"Spark/星火": "https://spark-api-open.xf-yun.com/v1/",
|
||||
"GLM/智谱清言": "https://open.bigmodel.cn/api/paas/v4/",
|
||||
"Moonshot/月之暗面": "https://api.moonshot.cn/v1",
|
||||
"Baichuan/百川": "https://api.baichuan-ai.com/v1/",
|
||||
"MiniMax/MiniMax": "https://api.minimax.chat/v1/",
|
||||
"StepFun/阶跃星辰": "https://api.stepfun.com/v1/",
|
||||
"SenseChat/日日新": "https://api.sensenova.cn/compatible-mode/v1"
|
||||
}
|
||||
actual_base_url = base_url_mapping.get(base_url.strip(), base_url)
|
||||
|
||||
# 对话历史和 payload 构建 (保持不变)
|
||||
if not enable_memory:
|
||||
self._conversation_history = []
|
||||
|
||||
if not hasattr(self, "_conversation_history"):
|
||||
self._conversation_history = []
|
||||
|
||||
if system_prompt and not any(msg["role"] == "system" for msg in self._conversation_history):
|
||||
self._conversation_history.append({"role": "system", "content": system_prompt})
|
||||
|
||||
# 避免重复添加内容
|
||||
# 修改对话历史添加逻辑
|
||||
if enable_memory:
|
||||
if not any(msg["role"] == "user" and msg["content"] == content for msg in self._conversation_history):
|
||||
self._conversation_history.append({"role": "user", "content": content})
|
||||
else:
|
||||
# 当禁用记忆时,总是创建新的对话历史
|
||||
self._conversation_history = [{"role": "user", "content": content}]
|
||||
# 重构消息格式化逻辑
|
||||
if enable_memory:
|
||||
# 使用对话历史生成消息
|
||||
formatted_messages = []
|
||||
for msg in self._conversation_history:
|
||||
if isinstance(msg["content"], list):
|
||||
formatted_messages.append({
|
||||
"role": msg["role"],
|
||||
"content": msg["content"]
|
||||
})
|
||||
else:
|
||||
formatted_messages.append(msg)
|
||||
else:
|
||||
# 当禁用记忆时,直接使用当前消息
|
||||
formatted_messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": content
|
||||
}
|
||||
]
|
||||
# 添加时间戳确保请求唯一性
|
||||
# 处理随机种子
|
||||
seed_value = seed if seed is not None else random.randint(1, 1000000)
|
||||
CATEGORY = "🚦ComfyUI_LLMs_Toolkit/Generate"
|
||||
|
||||
def __init__(self):
|
||||
self._conversation_history: List[Dict[str, Any]] = []
|
||||
self._request_start_time: float = 0.0
|
||||
|
||||
def _log_request_start(
|
||||
self,
|
||||
provider: ProviderConfig,
|
||||
model: str,
|
||||
system_prompt: Optional[str],
|
||||
prompt: str,
|
||||
image_attached: bool
|
||||
) -> None:
|
||||
"""Geek-style request logging with timing"""
|
||||
self._request_start_time = time.time()
|
||||
ts = time.strftime('%H:%M:%S')
|
||||
|
||||
payload = {
|
||||
"model": selected_model,
|
||||
"messages": formatted_messages,
|
||||
# Build context flags
|
||||
flags = []
|
||||
if system_prompt:
|
||||
flags.append('sys')
|
||||
if image_attached:
|
||||
flags.append('img')
|
||||
|
||||
flag_str = f"[{' '.join(flags)}]" if flags else ""
|
||||
|
||||
# Compact header
|
||||
print(f"[LLMs_Toolkit] {ts} → {provider.name}/{model or 'default'} {flag_str}")
|
||||
|
||||
# Content preview (indented)
|
||||
if system_prompt:
|
||||
sys_preview = system_prompt[:60].replace('\n', ' ')
|
||||
print(f" sys│ {sys_preview}...")
|
||||
|
||||
prompt_preview = prompt[:80].replace('\n', ' ')
|
||||
print(f" in │ {prompt_preview}...")
|
||||
|
||||
def _log_request_complete(
|
||||
self,
|
||||
response: str,
|
||||
input_tokens: int,
|
||||
output_tokens: int
|
||||
) -> None:
|
||||
"""Geek-style completion logging with metrics"""
|
||||
# Calculate elapsed time
|
||||
elapsed_ms = int((time.time() - self._request_start_time) * 1000)
|
||||
|
||||
# Format token counts (k suffix for thousands)
|
||||
in_tok = f"{input_tokens/1000:.1f}k" if input_tokens >= 1000 else str(input_tokens)
|
||||
out_tok = f"{output_tokens/1000:.1f}k" if output_tokens >= 1000 else str(output_tokens)
|
||||
|
||||
# Response preview
|
||||
preview = response[:80].replace('\n', ' ')
|
||||
|
||||
print(f" out│ {preview}...")
|
||||
print(f"[LLMs_Toolkit] {time.strftime('%H:%M:%S')} ← {in_tok}/{out_tok}t ({elapsed_ms}ms)\n")
|
||||
|
||||
async def _async_api_call(
|
||||
self,
|
||||
endpoint: str,
|
||||
payload: Dict[str, Any],
|
||||
api_key: str
|
||||
) -> Tuple[str, Dict[str, Any]]:
|
||||
"""Core async API call with proper error handling"""
|
||||
async with ClientSession() as session:
|
||||
try:
|
||||
async with session.post(
|
||||
f"{endpoint}/chat/completions",
|
||||
headers={
|
||||
"Content-Type": "application/json",
|
||||
"Authorization": f"Bearer {api_key}"
|
||||
},
|
||||
json=payload,
|
||||
timeout=60
|
||||
) as response:
|
||||
response.raise_for_status()
|
||||
data = await response.json()
|
||||
|
||||
content = data["choices"][0]["message"]["content"]
|
||||
|
||||
return content, data
|
||||
|
||||
except ClientError as e:
|
||||
raise Exception(f"API request failed: {str(e)}")
|
||||
|
||||
def _build_payload(
|
||||
self,
|
||||
model: str,
|
||||
messages: List[Dict[str, Any]],
|
||||
temperature: float,
|
||||
max_tokens: int
|
||||
) -> Dict[str, Any]:
|
||||
"""Build API request payload"""
|
||||
return {
|
||||
"model": model or "glm-4",
|
||||
"messages": messages,
|
||||
"temperature": temperature,
|
||||
"max_tokens": max_tokens,
|
||||
"request_id": f"req-{int(time.time() * 1000)}-{hash(str(content))}", # 唯一请求ID
|
||||
"timestamp": int(time.time() * 1000), # 毫秒级时间戳
|
||||
"seed": seed_value # 添加随机种子
|
||||
"request_id": f"req-{int(time.time() * 1000)}-{random.randint(1000, 9999)}",
|
||||
"timestamp": int(time.time() * 1000),
|
||||
"seed": random.randint(1, 1000000)
|
||||
}
|
||||
|
||||
def _manage_conversation_history(
|
||||
self,
|
||||
messages: List[Dict[str, Any]],
|
||||
enable_memory: bool
|
||||
) -> List[Dict[str, Any]]:
|
||||
"""Manage conversation history with memory support"""
|
||||
if not enable_memory:
|
||||
self._conversation_history = []
|
||||
return messages
|
||||
|
||||
# Append to history and return full context
|
||||
for msg in messages:
|
||||
if not any(
|
||||
h["role"] == msg["role"] and h["content"] == msg["content"]
|
||||
for h in self._conversation_history
|
||||
):
|
||||
self._conversation_history.append(msg)
|
||||
|
||||
return self._conversation_history
|
||||
|
||||
def generate(
|
||||
self,
|
||||
base_url: str,
|
||||
api_key: str,
|
||||
prompt: str,
|
||||
model: str,
|
||||
temperature: float,
|
||||
max_tokens: int,
|
||||
system_prompt: Optional[str] = None,
|
||||
prep_img: Optional[str] = None,
|
||||
enable_memory: bool = False,
|
||||
seed: int = 0
|
||||
) -> Tuple[str, int, int]:
|
||||
"""Main generation entry point"""
|
||||
|
||||
# Get provider configuration
|
||||
provider = ProviderRegistry.get_provider(base_url)
|
||||
|
||||
# Log request details
|
||||
self._log_request_start(
|
||||
provider=provider,
|
||||
model=model,
|
||||
system_prompt=system_prompt,
|
||||
prompt=prompt,
|
||||
image_attached=bool(prep_img)
|
||||
)
|
||||
|
||||
# Build message content
|
||||
content = MessageBuilder.build_content(prompt, prep_img)
|
||||
|
||||
# Build messages with system prompt
|
||||
messages = MessageBuilder.build_messages(content, system_prompt)
|
||||
|
||||
# Apply provider-specific adaptations
|
||||
messages = MessageBuilder.adapt_for_provider(messages, provider, prompt)
|
||||
|
||||
# Manage conversation history
|
||||
messages = self._manage_conversation_history(messages, enable_memory)
|
||||
|
||||
# Build request payload
|
||||
payload = self._build_payload(model, messages, temperature, max_tokens)
|
||||
|
||||
# Estimate input tokens
|
||||
input_tokens = TokenEstimator.estimate_input_tokens(
|
||||
prompt, system_prompt, prep_img
|
||||
)
|
||||
|
||||
if "spark-api-open.xf-yun.com" in actual_base_url or "api.baichuan-ai.com" in actual_base_url or "api.sensenova.cn" in actual_base_url:
|
||||
# 星火大模型需要 content 为字符串
|
||||
payload["messages"] = [
|
||||
{
|
||||
"role": "system",
|
||||
"content": system_prompt
|
||||
},
|
||||
{
|
||||
"role": "user",
|
||||
"content": prompt if isinstance(prompt, str) else prompt[0]["text"]
|
||||
}
|
||||
]
|
||||
else:
|
||||
# 其他模型保持现有结构
|
||||
payload["messages"] = formatted_messages
|
||||
|
||||
# 简化后的调试日志
|
||||
print(f"[DEBUG] Using model: {selected_model}")
|
||||
print(f"[DEBUG] Base URL: {actual_base_url}")
|
||||
|
||||
# 确保 temperature 和 max_tokens 参数符合范围
|
||||
if not isinstance(temperature, float):
|
||||
try:
|
||||
temperature = float(temperature)
|
||||
except ValueError:
|
||||
raise ValueError(f"temperature 参数无法转换为浮点数: {temperature}")
|
||||
if not (0.0 <= temperature <= 2.0):
|
||||
raise ValueError(f"temperature 参数超出范围: {temperature}")
|
||||
|
||||
try:
|
||||
max_tokens = int(max_tokens)
|
||||
except ValueError:
|
||||
raise ValueError(f"max_tokens 参数无法转换为整数: {max_tokens}")
|
||||
if not (1 <= max_tokens <= 4096):
|
||||
raise ValueError(f"max_tokens 参数超出范围: {max_tokens}")
|
||||
|
||||
# 移除完整的payload日志
|
||||
# 简化后的调用日志
|
||||
# 使用时间戳代替 uuid 生成唯一标识符
|
||||
print(f"[{time.strftime('%Y/%m/%d %H:%M:%S')}] INFO PromptTask {int(time.time())}")
|
||||
print(f"Input: {prompt}")
|
||||
print(f"HTTP Request: POST {actual_base_url}/chat/completions \"HTTP/1.1 200 OK\"")
|
||||
# Token 计算逻辑
|
||||
def count_tokens(content):
|
||||
return sum(len(str(item).split()) for item in content)
|
||||
|
||||
# 按字符分割
|
||||
input_tokens = len(prompt)
|
||||
if system_prompt:
|
||||
input_tokens += len(system_prompt)
|
||||
if prep_img:
|
||||
# 根据 prep_img 计算 token
|
||||
if isinstance(prep_img, str): # Base64 编码的字符串
|
||||
# 估算 token 数量(基于字符串长度)
|
||||
image_tokens = len(prep_img) // 1000
|
||||
else:
|
||||
image_tokens = 0 # 未知类型,默认为 0
|
||||
input_tokens += image_tokens
|
||||
|
||||
|
||||
try:
|
||||
time.sleep(1)
|
||||
import asyncio
|
||||
|
||||
loop = asyncio.new_event_loop()
|
||||
asyncio.set_event_loop(loop)
|
||||
try:
|
||||
task = loop.create_task(self.async_generate(payload, actual_base_url, api_key))
|
||||
response_content, data = loop.run_until_complete(task)
|
||||
# Extract completion_tokens from API response
|
||||
completion_tokens = data.get("usage", {}).get("completion_tokens", 0)
|
||||
return [response_content, int(input_tokens), int(completion_tokens)]
|
||||
except Exception as e:
|
||||
print(f"[ERROR] 异步任务失败: {str(e)}")
|
||||
raise
|
||||
finally:
|
||||
try:
|
||||
if hasattr(loop, 'shutdown_asyncgens'):
|
||||
loop.run_until_complete(loop.shutdown_asyncgens())
|
||||
# Ensure all tasks are done before closing the loop
|
||||
pending = asyncio.all_tasks(loop)
|
||||
if pending:
|
||||
print(f"[WARNING] There are {len(pending)} pending tasks. Waiting for them to complete...")
|
||||
loop.run_until_complete(asyncio.gather(*pending))
|
||||
finally:
|
||||
loop.close()
|
||||
# Use asyncio.run() for clean event loop management
|
||||
response_content, data = asyncio.run(
|
||||
self._async_api_call(provider.base_url, payload, api_key)
|
||||
)
|
||||
|
||||
# Extract actual token usage from response
|
||||
output_tokens = data.get("usage", {}).get("completion_tokens", 0)
|
||||
|
||||
# Log completion
|
||||
self._log_request_complete(response_content, input_tokens, output_tokens)
|
||||
|
||||
return (response_content, int(input_tokens), int(output_tokens))
|
||||
|
||||
except Exception as e:
|
||||
raise Exception(f"请求失败: {str(e)}")
|
||||
print(f"[LLMs_Toolkit] ✗ {str(e)}")
|
||||
raise
|
||||
|
||||
|
||||
# 注册节点 (保持不变)
|
||||
# ComfyUI node registration
|
||||
NODE_CLASS_MAPPINGS = {"OpenAICompatibleLoader": OpenAICompatibleLoader}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"OpenAICompatibleLoader": "OpenAI Compatible Adapter"}
|
||||
|
||||
WEB_DIRECTORY = "./web"
|
||||
__all__ = ['NODE_CLASS_MAPPINGS', 'NODE_DISPLAY_NAME_MAPPINGS']
|
||||
__all__ = ["NODE_CLASS_MAPPINGS", "NODE_DISPLAY_NAME_MAPPINGS"]
|
||||
|
||||
@@ -30,7 +30,7 @@ class ImagePreprocessor:
|
||||
quality_map = {"High": 95, "Medium": 75, "Low": 50}
|
||||
quality_str = quality # Ensure quality is treated as a string
|
||||
quality_val = quality_map.get(quality_str, 95) # Default to High if invalid value
|
||||
print(f"Selected quality: {quality_val}") # Debugging line
|
||||
print(f"[LLMs_Toolkit] quality={quality_val}")
|
||||
|
||||
if image is None:
|
||||
raise ValueError("Image input cannot be None")
|
||||
@@ -50,7 +50,7 @@ class ImagePreprocessor:
|
||||
# Resize image based on quality
|
||||
size_map = {"High": 1024, "Medium": 768, "Low": 512}
|
||||
max_size = size_map.get(quality_str, 1024)
|
||||
print(f"Resizing image to max dimension: {max_size}")
|
||||
print(f"[LLMs_Toolkit] resize={max_size}px")
|
||||
image.thumbnail((max_size, max_size), Image.Resampling.LANCZOS)
|
||||
|
||||
# Convert PIL image to base64 string
|
||||
@@ -58,8 +58,8 @@ class ImagePreprocessor:
|
||||
image.save(buffered, format=format, quality=quality_val)
|
||||
img_str = base64.b64encode(buffered.getvalue()).decode("utf-8")
|
||||
image_url = f"data:image/{format.lower()};base64,{img_str}"
|
||||
print(f"Image size with quality {quality}: {buffered.tell()} bytes")
|
||||
print(f"Generated image URL: {image_url[:50]}...") # 打印生成的图像 URL 前 50 个字符
|
||||
size_kb = buffered.tell() / 1024
|
||||
print(f"[LLMs_Toolkit] encoded={size_kb:.1f}KB {format}")
|
||||
|
||||
return (image_url,)
|
||||
|
||||
|
||||
Reference in New Issue
Block a user