feat: add images to Readme
This commit is contained in:
 KingManiya
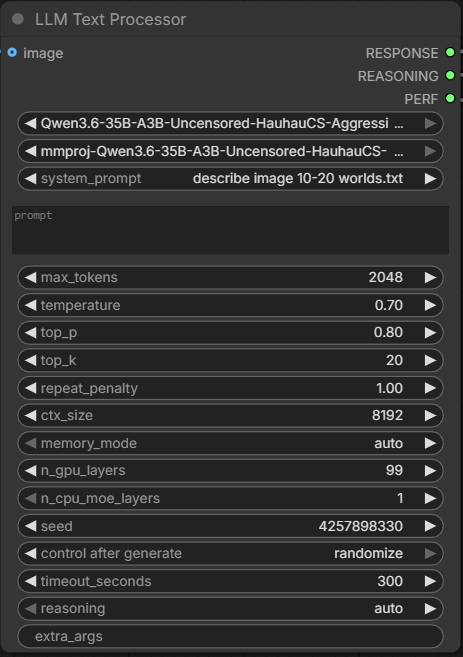
@@ -8,6 +8,8 @@ translation, captioning, extraction, and other text processing tasks inside
|
||||
ComfyUI. It discovers local GGUF models from `ComfyUI/models/LLM`, and it can
|
||||
also accept an image for multimodal models that use an external `mmproj`.
|
||||
|
||||
|
||||
|
||||
## Features
|
||||
|
||||
- Text generation and text transformation with local GGUF models
|
||||
@@ -63,6 +65,9 @@ LLM Text Processor -> LLM Text Processor
|
||||
|
||||
No extra setup is needed for basic use.
|
||||
|
||||
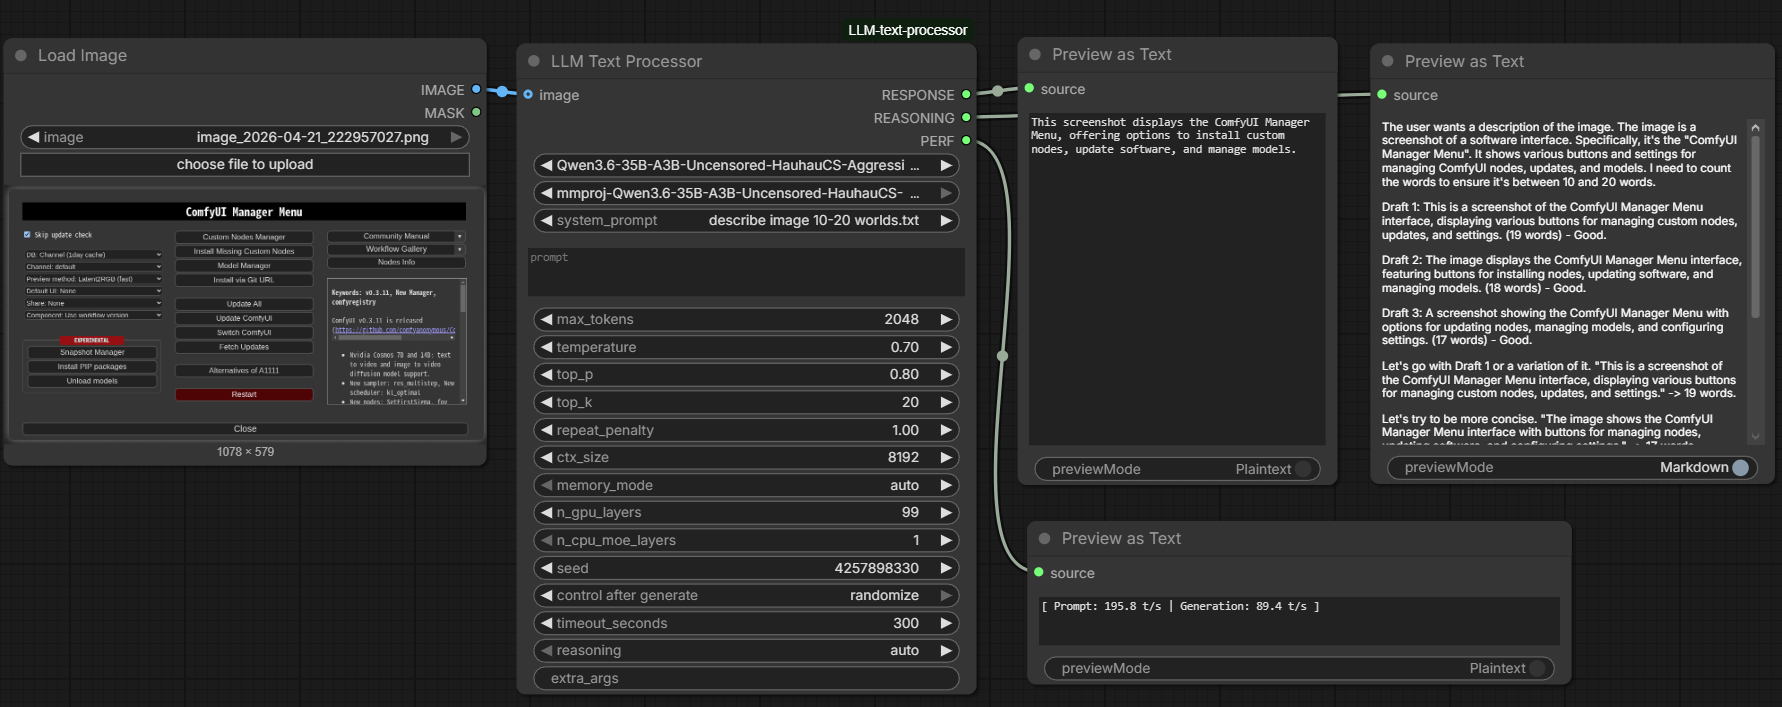
### Example workflow
|
||||
|
||||
|
||||
## llama.cpp
|
||||
|
||||
The node uses official llama.cpp release binaries. Automatic setup is currently
|
||||
|
||||
Reference in New Issue
Block a user