feat: add support batch images. v1.3.0
This commit is contained in:
 KingManiya
@@ -6,14 +6,16 @@ Qwen3-VL, Qwen3.5, Qwen3.6, Gemma 4, and gpt-oss.
|
||||
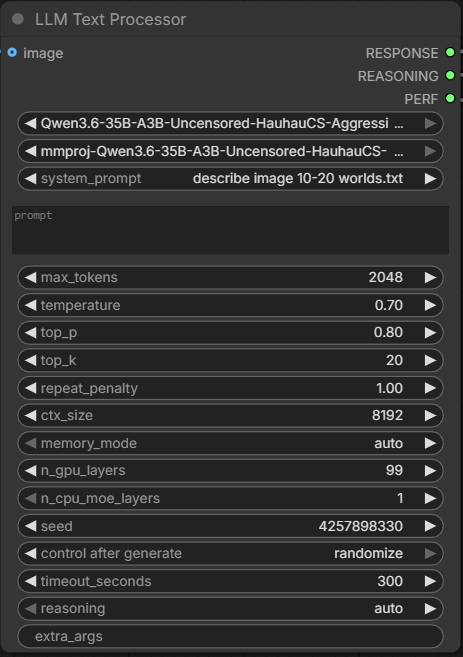
This extension adds a local LLM node for prompt writing, prompt rewriting,
|
||||
translation, captioning, extraction, and other text processing tasks inside
|
||||
ComfyUI. It discovers local GGUF models from `ComfyUI/models/LLM`, and it can
|
||||
also accept an image for multimodal models that use an external `mmproj`.
|
||||
also accept a single image or a ComfyUI image batch for multimodal models that
|
||||
use an external `mmproj`.
|
||||
|
||||
|
||||
|
||||
## Features
|
||||
|
||||
- Text generation and text transformation with local GGUF models
|
||||
- Optional image input for multimodal llama.cpp models that use `mmproj`
|
||||
- Optional image input for multimodal llama.cpp models that use `mmproj`,
|
||||
including multi-image batches
|
||||
- Separate `RESPONSE` and `REASONING` outputs
|
||||
- System prompt presets from text files
|
||||
- Recursive model discovery from `ComfyUI/models/LLM`
|
||||
@@ -106,7 +108,8 @@ The `model` dropdown shows model `.gguf` files. The `mmproj` dropdown shows
|
||||
vision projector files and `none`.
|
||||
|
||||
For image workflows, choose the `mmproj` file that belongs to the selected
|
||||
model. The node uses only the first image from a ComfyUI image batch.
|
||||
model. You can connect either one image or a ComfyUI image batch; batch items
|
||||
are sent together in the same llama.cpp request.
|
||||
|
||||
## System Prompt Presets
|
||||
|
||||
@@ -204,7 +207,7 @@ Reference: [gpt-oss docs](https://github.com/openai/gpt-oss)
|
||||
| Input | Description |
|
||||
| --- | --- |
|
||||
| `model` | GGUF model file from `ComfyUI/models/LLM`. |
|
||||
| `mmproj` | Vision projector GGUF. Required when using image input. |
|
||||
| `mmproj` | Vision projector GGUF. Required when using image input, whether it is one image or a batch. |
|
||||
| `system_prompt` | Prompt preset from `models/LLM/prompts`, or `none`. |
|
||||
| `prompt` | User prompt sent to the selected model. |
|
||||
| `max_tokens` | Maximum generated tokens. |
|
||||
@@ -219,7 +222,7 @@ Reference: [gpt-oss docs](https://github.com/openai/gpt-oss)
|
||||
| `seed` | Random seed. Use `-1` for a random seed. |
|
||||
| `timeout_seconds` | Maximum runtime before generation is stopped. |
|
||||
| `reasoning` | Reasoning output mode: `auto`, `on`, or `off`. |
|
||||
| `image` | Optional ComfyUI image input. Uses the first image in a batch. |
|
||||
| `image` | Optional image input. Accepts a single image or a ComfyUI batch, and sends the batch together to llama.cpp. |
|
||||
| `enable_processing` | When enabled, the node runs normally. When disabled, the node forwards `prompt` directly to `RESPONSE` and skips all model checks and llama.cpp execution. |
|
||||
| `extra_args` | Optional advanced llama.cpp parameters. Leave empty for normal use. |
|
||||
|
||||
|
||||
+13
-10
@@ -27,14 +27,10 @@ LLAMA_SEED_MODULUS = 2**32
|
||||
MAX_LLAMA_SEED = LLAMA_SEED_MODULUS - 1
|
||||
|
||||
|
||||
def tensor_to_temp_png(image) -> Path:
|
||||
def _tensor_to_temp_png(tensor) -> Path:
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
# ComfyUI IMAGE is normally B,H,W,C. The node uses the first batch item in v1.
|
||||
tensor = image
|
||||
if hasattr(tensor, "dim") and tensor.dim() == 4:
|
||||
tensor = tensor[0]
|
||||
array = (tensor.detach().cpu().numpy() * 255).clip(0, 255).astype(np.uint8)
|
||||
pil_image = Image.fromarray(array)
|
||||
fd, path = tempfile.mkstemp(prefix="llm-text-processor-", suffix=".png")
|
||||
@@ -43,6 +39,13 @@ def tensor_to_temp_png(image) -> Path:
|
||||
return Path(path)
|
||||
|
||||
|
||||
def tensor_to_temp_pngs(image) -> list[Path]:
|
||||
# ComfyUI IMAGE is normally B,H,W,C. Each batch item becomes one CLI image.
|
||||
if hasattr(image, "dim") and image.dim() == 4:
|
||||
return [_tensor_to_temp_png(tensor) for tensor in image]
|
||||
return [_tensor_to_temp_png(image)]
|
||||
|
||||
|
||||
def _write_temp_text_file(prefix: str, text: str) -> Path:
|
||||
fd, path = tempfile.mkstemp(prefix=prefix, suffix=".txt")
|
||||
os.close(fd)
|
||||
@@ -92,12 +95,12 @@ def build_command(
|
||||
) -> tuple[list[str], tuple[Path | None, ...]]:
|
||||
cleanup_paths = []
|
||||
cli_paths = ensure_llama_cli_paths()
|
||||
image_path = None
|
||||
image_paths = []
|
||||
if image is not None:
|
||||
if mmproj_path is None:
|
||||
raise ValueError("Image input requires a selected mmproj GGUF file.")
|
||||
image_path = tensor_to_temp_png(image)
|
||||
cleanup_paths.append(image_path)
|
||||
image_paths = tensor_to_temp_pngs(image)
|
||||
cleanup_paths.extend(image_paths)
|
||||
|
||||
prompt_path = _write_prompt_file(prompt)
|
||||
cleanup_paths.append(prompt_path)
|
||||
@@ -128,9 +131,9 @@ def build_command(
|
||||
|
||||
command.extend(["-f", str(prompt_path)])
|
||||
|
||||
if image_path:
|
||||
if image_paths:
|
||||
command.extend(["--mmproj", str(mmproj_path)])
|
||||
command.extend(["--image", str(image_path)])
|
||||
command.extend(["--image", ",".join(str(path) for path in image_paths)])
|
||||
|
||||
if extra_args:
|
||||
command.extend(extra_args)
|
||||
|
||||
@@ -27,7 +27,7 @@ class LLMTextProcessor:
|
||||
}),
|
||||
"mmproj": (mmproj_options(), {
|
||||
"default": NO_MMPROJ,
|
||||
"tooltip": "Vision projector GGUF. Required when an image is connected.",
|
||||
"tooltip": "Vision projector GGUF. Required when one or more images are connected.",
|
||||
}),
|
||||
"system_prompt": (system_prompt_options(), {
|
||||
"tooltip": "System prompt preset from ComfyUI/models/LLM/prompts, or none.",
|
||||
@@ -74,9 +74,9 @@ class LLMTextProcessor:
|
||||
"ctx_size": ("INT", {
|
||||
"default": 8192,
|
||||
"min": 512,
|
||||
"max": 131072,
|
||||
"max": 1048576,
|
||||
"step": 512,
|
||||
"tooltip": "Context window size in tokens.",
|
||||
"tooltip": "Context window size in tokens. Use a value supported by the selected GGUF; larger context uses more VRAM.",
|
||||
}),
|
||||
"memory_mode": ([
|
||||
"auto",
|
||||
@@ -121,7 +121,7 @@ class LLMTextProcessor:
|
||||
},
|
||||
"optional": {
|
||||
"image": ("IMAGE", {
|
||||
"tooltip": "Optional ComfyUI image input. Uses the first image in the batch.",
|
||||
"tooltip": "Optional image input. A single image or ComfyUI batch is passed to llama.cpp.",
|
||||
}),
|
||||
"enable_processing": ("BOOLEAN", {
|
||||
"default": True,
|
||||
|
||||
+1
-1
@@ -1,7 +1,7 @@
|
||||
[project]
|
||||
name = "ComfyUI-LLM-text-processor"
|
||||
description = "Process text and images with GGUF LLMs in ComfyUI using llama.cpp, including Qwen3-VL, Qwen3.5, Qwen3.6, Gemma 4, and gpt-oss."
|
||||
version = "1.2.0"
|
||||
version = "1.3.0"
|
||||
license = {file = "LICENSE"}
|
||||
dependencies = ["numpy", "Pillow"]
|
||||
|
||||
|
||||
Reference in New Issue
Block a user