'update'
This commit is contained in:
 wailovet
@@ -164,3 +164,10 @@ kohya_ss
|
||||
copytoww.bat
|
||||
exclude.txt
|
||||
.vscode/settings.json
|
||||
*.safetensors
|
||||
*.ckpt
|
||||
*.bin
|
||||
*.onnx
|
||||
*.msgpack
|
||||
*.onnx_data
|
||||
configs/models_config/**/*.png
|
||||
|
||||
+87
-3
@@ -78,14 +78,12 @@ NODE_DISPLAY_NAME_MAPPINGS["MZ_ImagesCopyWorkspace"] = f"{AUTHOR_NAME} - ImagesC
|
||||
|
||||
|
||||
class MZ_KohyaSSUseConfig:
|
||||
|
||||
train_config_template_dir = os.path.join(
|
||||
os.path.dirname(__file__), "configs", "kohya_ss_lora"
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
|
||||
train_config_templates = os.listdir(s.train_config_template_dir)
|
||||
# 去掉json后缀
|
||||
train_config_templates = [os.path.splitext(x)[0]
|
||||
@@ -96,8 +94,15 @@ class MZ_KohyaSSUseConfig:
|
||||
"workspace_config": ("MZ_TT_SS_WorkspaceConfig",),
|
||||
"workspace_images_dir": ("STRING", {"forceInput": True}),
|
||||
"train_config_template": (train_config_templates,),
|
||||
"ckpt_name": (folder_paths.get_filename_list("checkpoints"), )
|
||||
"ckpt_name": (folder_paths.get_filename_list("checkpoints"), ),
|
||||
"max_train_steps": ("INT", {"default": 300}),
|
||||
"max_train_epochs": ("INT", {"default": 0}),
|
||||
"save_every_n_epochs": ("INT", {"default": 20}),
|
||||
"learning_rate": ("STRING", {"default": "1e-5"}),
|
||||
},
|
||||
"optional": {
|
||||
"advanced_config": ("MZ_TT_SS_AdvConfig",),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = (f"MZ_TT_SS_TrainConfig",)
|
||||
@@ -116,6 +121,85 @@ NODE_CLASS_MAPPINGS["MZ_KohyaSSUseConfig"] = MZ_KohyaSSUseConfig
|
||||
NODE_DISPLAY_NAME_MAPPINGS["MZ_KohyaSSUseConfig"] = f"{AUTHOR_NAME} - KohyaSSUseConfig"
|
||||
|
||||
|
||||
class MZ_KohyaSSAdvConfig:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"xformers": (["enable", "disable"], {"default": "enable"}),
|
||||
"sdpa": (["enable", "disable"], {"default": "disable"}),
|
||||
"fp8_base": (["enable", "disable"], {"default": "disable"}),
|
||||
"mixed_precision": (["no", "fp16", "bf16"], {"default": "fp16"}),
|
||||
"cache_latents": (["enable", "disable"], {"default": "enable"}),
|
||||
"cache_latents_to_disk": (["enable", "disable"], {"default": "enable"}),
|
||||
"network_dim": ("INT", {"default": 16}),
|
||||
"network_alpha": ("INT", {"default": 8}),
|
||||
"network_module": ([
|
||||
"networks.lora",
|
||||
"networks.dylora",
|
||||
"networks.oft",
|
||||
], {"default": "networks.lora"}),
|
||||
"network_train_unet_only": (["enable", "disable"], {"default": "enable"}),
|
||||
# linear, cosine, cosine_with_restarts, polynomial, constant (default), constant_with_warmup, adafactor
|
||||
"lr_scheduler": ([
|
||||
"linear",
|
||||
"cosine",
|
||||
"cosine_with_restarts",
|
||||
"polynomial",
|
||||
"constant",
|
||||
"constant_with_warmup",
|
||||
"adafactor",
|
||||
], {"default": "cosine"}),
|
||||
"lr_scheduler_num_cycles": ("INT", {"default": 1}),
|
||||
# AdamW (default), AdamW8bit, PagedAdamW, PagedAdamW8bit, PagedAdamW32bit, Lion8bit, PagedLion8bit, Lion, SGDNesterov, SGDNesterov8bit, DAdaptation(DAdaptAdamPreprint), DAdaptAdaGrad, DAdaptAdam, DAdaptAdan, DAdaptAdanIP, DAdaptLion, DAdaptSGD, AdaFactor
|
||||
"optimizer_type": ([
|
||||
"AdamW",
|
||||
"AdamW8bit",
|
||||
"PagedAdamW",
|
||||
"PagedAdamW8bit",
|
||||
"PagedAdamW32bit",
|
||||
"Lion8bit",
|
||||
"PagedLion8bit",
|
||||
"Lion",
|
||||
"SGDNesterov",
|
||||
"SGDNesterov8bit",
|
||||
"DAdaptation",
|
||||
"DAdaptAdaGrad",
|
||||
"DAdaptAdam",
|
||||
"DAdaptAdan",
|
||||
"DAdaptAdanIP",
|
||||
"DAdaptLion",
|
||||
"DAdaptSGD",
|
||||
"AdaFactor",
|
||||
], {"default": "AdamW"}),
|
||||
"lr_warmup_steps": ("INT", {"default": 0}),
|
||||
"unet_lr": ("STRING", {"default": ""}),
|
||||
"text_encoder_lr": ("STRING", {"default": ""}),
|
||||
"shuffle_caption": (["enable", "disable"], {"default": "enable"}),
|
||||
"save_precision": (["float", "fp16", "bf16"], {"default": "fp16"}),
|
||||
"persistent_data_loader_workers": (["enable", "disable"], {"default": "enable"}),
|
||||
"no_metadata": (["enable", "disable"], {"default": "enable"}),
|
||||
"noise_offset": ("FLOAT", {"default": 0.1}),
|
||||
"no_half_vae": (["enable", "disable"], {"default": "enable"}),
|
||||
"lowram": (["enable", "disable"], {"default": "disable"}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("MZ_TT_SS_AdvConfig",)
|
||||
RETURN_NAMES = ("advanced_config",)
|
||||
|
||||
FUNCTION = "start"
|
||||
|
||||
CATEGORY = CATEGORY_NAME
|
||||
|
||||
def start(self, **kwargs):
|
||||
return (kwargs,)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS["MZ_KohyaSSAdvConfig"] = MZ_KohyaSSAdvConfig
|
||||
NODE_DISPLAY_NAME_MAPPINGS["MZ_KohyaSSAdvConfig"] = f"{AUTHOR_NAME} - KohyaSSAdvConfig"
|
||||
|
||||
|
||||
class MZ_KohyaSSTrain:
|
||||
|
||||
@classmethod
|
||||
|
||||
@@ -15,10 +15,9 @@
|
||||
"network_alpha": "8",
|
||||
"network_module": "networks.lora",
|
||||
"network_train_unet_only": true,
|
||||
"learning_rate": "1e-5",
|
||||
"lr_scheduler": "cosine_with_restarts",
|
||||
"optimizer_type": "AdamW",
|
||||
"unet_lr": "1e-5",
|
||||
"text_encoder_lr": "1e-5",
|
||||
"save_every_n_epochs": "20",
|
||||
"shuffle_caption": true,
|
||||
"lr_warmup_steps": "0",
|
||||
|
||||
@@ -0,0 +1,35 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
v1-5-pruned-emaonly.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
v1-5-pruned.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
@@ -0,0 +1,207 @@
|
||||
---
|
||||
license: creativeml-openrail-m
|
||||
tags:
|
||||
- stable-diffusion
|
||||
- stable-diffusion-diffusers
|
||||
- text-to-image
|
||||
inference: true
|
||||
extra_gated_prompt: |-
|
||||
This model is open access and available to all, with a CreativeML OpenRAIL-M license further specifying rights and usage.
|
||||
The CreativeML OpenRAIL License specifies:
|
||||
|
||||
1. You can't use the model to deliberately produce nor share illegal or harmful outputs or content
|
||||
2. CompVis claims no rights on the outputs you generate, you are free to use them and are accountable for their use which must not go against the provisions set in the license
|
||||
3. You may re-distribute the weights and use the model commercially and/or as a service. If you do, please be aware you have to include the same use restrictions as the ones in the license and share a copy of the CreativeML OpenRAIL-M to all your users (please read the license entirely and carefully)
|
||||
Please read the full license carefully here: https://huggingface.co/spaces/CompVis/stable-diffusion-license
|
||||
|
||||
extra_gated_heading: Please read the LICENSE to access this model
|
||||
---
|
||||
|
||||
# Stable Diffusion v1-5 Model Card
|
||||
|
||||
Stable Diffusion is a latent text-to-image diffusion model capable of generating photo-realistic images given any text input.
|
||||
For more information about how Stable Diffusion functions, please have a look at [🤗's Stable Diffusion blog](https://huggingface.co/blog/stable_diffusion).
|
||||
|
||||
The **Stable-Diffusion-v1-5** checkpoint was initialized with the weights of the [Stable-Diffusion-v1-2](https:/steps/huggingface.co/CompVis/stable-diffusion-v1-2)
|
||||
checkpoint and subsequently fine-tuned on 595k steps at resolution 512x512 on "laion-aesthetics v2 5+" and 10% dropping of the text-conditioning to improve [classifier-free guidance sampling](https://arxiv.org/abs/2207.12598).
|
||||
|
||||
You can use this both with the [🧨Diffusers library](https://github.com/huggingface/diffusers) and the [RunwayML GitHub repository](https://github.com/runwayml/stable-diffusion).
|
||||
|
||||
### Diffusers
|
||||
```py
|
||||
from diffusers import StableDiffusionPipeline
|
||||
import torch
|
||||
|
||||
model_id = "runwayml/stable-diffusion-v1-5"
|
||||
pipe = StableDiffusionPipeline.from_pretrained(model_id, torch_dtype=torch.float16)
|
||||
pipe = pipe.to("cuda")
|
||||
|
||||
prompt = "a photo of an astronaut riding a horse on mars"
|
||||
image = pipe(prompt).images[0]
|
||||
|
||||
image.save("astronaut_rides_horse.png")
|
||||
```
|
||||
For more detailed instructions, use-cases and examples in JAX follow the instructions [here](https://github.com/huggingface/diffusers#text-to-image-generation-with-stable-diffusion)
|
||||
|
||||
### Original GitHub Repository
|
||||
|
||||
1. Download the weights
|
||||
- [v1-5-pruned-emaonly.ckpt](https://huggingface.co/runwayml/stable-diffusion-v1-5/resolve/main/v1-5-pruned-emaonly.ckpt) - 4.27GB, ema-only weight. uses less VRAM - suitable for inference
|
||||
- [v1-5-pruned.ckpt](https://huggingface.co/runwayml/stable-diffusion-v1-5/resolve/main/v1-5-pruned.ckpt) - 7.7GB, ema+non-ema weights. uses more VRAM - suitable for fine-tuning
|
||||
|
||||
2. Follow instructions [here](https://github.com/runwayml/stable-diffusion).
|
||||
|
||||
## Model Details
|
||||
- **Developed by:** Robin Rombach, Patrick Esser
|
||||
- **Model type:** Diffusion-based text-to-image generation model
|
||||
- **Language(s):** English
|
||||
- **License:** [The CreativeML OpenRAIL M license](https://huggingface.co/spaces/CompVis/stable-diffusion-license) is an [Open RAIL M license](https://www.licenses.ai/blog/2022/8/18/naming-convention-of-responsible-ai-licenses), adapted from the work that [BigScience](https://bigscience.huggingface.co/) and [the RAIL Initiative](https://www.licenses.ai/) are jointly carrying in the area of responsible AI licensing. See also [the article about the BLOOM Open RAIL license](https://bigscience.huggingface.co/blog/the-bigscience-rail-license) on which our license is based.
|
||||
- **Model Description:** This is a model that can be used to generate and modify images based on text prompts. It is a [Latent Diffusion Model](https://arxiv.org/abs/2112.10752) that uses a fixed, pretrained text encoder ([CLIP ViT-L/14](https://arxiv.org/abs/2103.00020)) as suggested in the [Imagen paper](https://arxiv.org/abs/2205.11487).
|
||||
- **Resources for more information:** [GitHub Repository](https://github.com/CompVis/stable-diffusion), [Paper](https://arxiv.org/abs/2112.10752).
|
||||
- **Cite as:**
|
||||
|
||||
@InProceedings{Rombach_2022_CVPR,
|
||||
author = {Rombach, Robin and Blattmann, Andreas and Lorenz, Dominik and Esser, Patrick and Ommer, Bj\"orn},
|
||||
title = {High-Resolution Image Synthesis With Latent Diffusion Models},
|
||||
booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
|
||||
month = {June},
|
||||
year = {2022},
|
||||
pages = {10684-10695}
|
||||
}
|
||||
|
||||
# Uses
|
||||
|
||||
## Direct Use
|
||||
The model is intended for research purposes only. Possible research areas and
|
||||
tasks include
|
||||
|
||||
- Safe deployment of models which have the potential to generate harmful content.
|
||||
- Probing and understanding the limitations and biases of generative models.
|
||||
- Generation of artworks and use in design and other artistic processes.
|
||||
- Applications in educational or creative tools.
|
||||
- Research on generative models.
|
||||
|
||||
Excluded uses are described below.
|
||||
|
||||
### Misuse, Malicious Use, and Out-of-Scope Use
|
||||
_Note: This section is taken from the [DALLE-MINI model card](https://huggingface.co/dalle-mini/dalle-mini), but applies in the same way to Stable Diffusion v1_.
|
||||
|
||||
|
||||
The model should not be used to intentionally create or disseminate images that create hostile or alienating environments for people. This includes generating images that people would foreseeably find disturbing, distressing, or offensive; or content that propagates historical or current stereotypes.
|
||||
|
||||
#### Out-of-Scope Use
|
||||
The model was not trained to be factual or true representations of people or events, and therefore using the model to generate such content is out-of-scope for the abilities of this model.
|
||||
|
||||
#### Misuse and Malicious Use
|
||||
Using the model to generate content that is cruel to individuals is a misuse of this model. This includes, but is not limited to:
|
||||
|
||||
- Generating demeaning, dehumanizing, or otherwise harmful representations of people or their environments, cultures, religions, etc.
|
||||
- Intentionally promoting or propagating discriminatory content or harmful stereotypes.
|
||||
- Impersonating individuals without their consent.
|
||||
- Sexual content without consent of the people who might see it.
|
||||
- Mis- and disinformation
|
||||
- Representations of egregious violence and gore
|
||||
- Sharing of copyrighted or licensed material in violation of its terms of use.
|
||||
- Sharing content that is an alteration of copyrighted or licensed material in violation of its terms of use.
|
||||
|
||||
## Limitations and Bias
|
||||
|
||||
### Limitations
|
||||
|
||||
- The model does not achieve perfect photorealism
|
||||
- The model cannot render legible text
|
||||
- The model does not perform well on more difficult tasks which involve compositionality, such as rendering an image corresponding to “A red cube on top of a blue sphere”
|
||||
- Faces and people in general may not be generated properly.
|
||||
- The model was trained mainly with English captions and will not work as well in other languages.
|
||||
- The autoencoding part of the model is lossy
|
||||
- The model was trained on a large-scale dataset
|
||||
[LAION-5B](https://laion.ai/blog/laion-5b/) which contains adult material
|
||||
and is not fit for product use without additional safety mechanisms and
|
||||
considerations.
|
||||
- No additional measures were used to deduplicate the dataset. As a result, we observe some degree of memorization for images that are duplicated in the training data.
|
||||
The training data can be searched at [https://rom1504.github.io/clip-retrieval/](https://rom1504.github.io/clip-retrieval/) to possibly assist in the detection of memorized images.
|
||||
|
||||
### Bias
|
||||
|
||||
While the capabilities of image generation models are impressive, they can also reinforce or exacerbate social biases.
|
||||
Stable Diffusion v1 was trained on subsets of [LAION-2B(en)](https://laion.ai/blog/laion-5b/),
|
||||
which consists of images that are primarily limited to English descriptions.
|
||||
Texts and images from communities and cultures that use other languages are likely to be insufficiently accounted for.
|
||||
This affects the overall output of the model, as white and western cultures are often set as the default. Further, the
|
||||
ability of the model to generate content with non-English prompts is significantly worse than with English-language prompts.
|
||||
|
||||
### Safety Module
|
||||
|
||||
The intended use of this model is with the [Safety Checker](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/safety_checker.py) in Diffusers.
|
||||
This checker works by checking model outputs against known hard-coded NSFW concepts.
|
||||
The concepts are intentionally hidden to reduce the likelihood of reverse-engineering this filter.
|
||||
Specifically, the checker compares the class probability of harmful concepts in the embedding space of the `CLIPTextModel` *after generation* of the images.
|
||||
The concepts are passed into the model with the generated image and compared to a hand-engineered weight for each NSFW concept.
|
||||
|
||||
|
||||
## Training
|
||||
|
||||
**Training Data**
|
||||
The model developers used the following dataset for training the model:
|
||||
|
||||
- LAION-2B (en) and subsets thereof (see next section)
|
||||
|
||||
**Training Procedure**
|
||||
Stable Diffusion v1-5 is a latent diffusion model which combines an autoencoder with a diffusion model that is trained in the latent space of the autoencoder. During training,
|
||||
|
||||
- Images are encoded through an encoder, which turns images into latent representations. The autoencoder uses a relative downsampling factor of 8 and maps images of shape H x W x 3 to latents of shape H/f x W/f x 4
|
||||
- Text prompts are encoded through a ViT-L/14 text-encoder.
|
||||
- The non-pooled output of the text encoder is fed into the UNet backbone of the latent diffusion model via cross-attention.
|
||||
- The loss is a reconstruction objective between the noise that was added to the latent and the prediction made by the UNet.
|
||||
|
||||
Currently six Stable Diffusion checkpoints are provided, which were trained as follows.
|
||||
- [`stable-diffusion-v1-1`](https://huggingface.co/CompVis/stable-diffusion-v1-1): 237,000 steps at resolution `256x256` on [laion2B-en](https://huggingface.co/datasets/laion/laion2B-en).
|
||||
194,000 steps at resolution `512x512` on [laion-high-resolution](https://huggingface.co/datasets/laion/laion-high-resolution) (170M examples from LAION-5B with resolution `>= 1024x1024`).
|
||||
- [`stable-diffusion-v1-2`](https://huggingface.co/CompVis/stable-diffusion-v1-2): Resumed from `stable-diffusion-v1-1`.
|
||||
515,000 steps at resolution `512x512` on "laion-improved-aesthetics" (a subset of laion2B-en,
|
||||
filtered to images with an original size `>= 512x512`, estimated aesthetics score `> 5.0`, and an estimated watermark probability `< 0.5`. The watermark estimate is from the LAION-5B metadata, the aesthetics score is estimated using an [improved aesthetics estimator](https://github.com/christophschuhmann/improved-aesthetic-predictor)).
|
||||
- [`stable-diffusion-v1-3`](https://huggingface.co/CompVis/stable-diffusion-v1-3): Resumed from `stable-diffusion-v1-2` - 195,000 steps at resolution `512x512` on "laion-improved-aesthetics" and 10 % dropping of the text-conditioning to improve [classifier-free guidance sampling](https://arxiv.org/abs/2207.12598).
|
||||
- [`stable-diffusion-v1-4`](https://huggingface.co/CompVis/stable-diffusion-v1-4) Resumed from `stable-diffusion-v1-2` - 225,000 steps at resolution `512x512` on "laion-aesthetics v2 5+" and 10 % dropping of the text-conditioning to improve [classifier-free guidance sampling](https://arxiv.org/abs/2207.12598).
|
||||
- [`stable-diffusion-v1-5`](https://huggingface.co/runwayml/stable-diffusion-v1-5) Resumed from `stable-diffusion-v1-2` - 595,000 steps at resolution `512x512` on "laion-aesthetics v2 5+" and 10 % dropping of the text-conditioning to improve [classifier-free guidance sampling](https://arxiv.org/abs/2207.12598).
|
||||
- [`stable-diffusion-inpainting`](https://huggingface.co/runwayml/stable-diffusion-inpainting) Resumed from `stable-diffusion-v1-5` - then 440,000 steps of inpainting training at resolution 512x512 on “laion-aesthetics v2 5+” and 10% dropping of the text-conditioning. For inpainting, the UNet has 5 additional input channels (4 for the encoded masked-image and 1 for the mask itself) whose weights were zero-initialized after restoring the non-inpainting checkpoint. During training, we generate synthetic masks and in 25% mask everything.
|
||||
|
||||
- **Hardware:** 32 x 8 x A100 GPUs
|
||||
- **Optimizer:** AdamW
|
||||
- **Gradient Accumulations**: 2
|
||||
- **Batch:** 32 x 8 x 2 x 4 = 2048
|
||||
- **Learning rate:** warmup to 0.0001 for 10,000 steps and then kept constant
|
||||
|
||||
## Evaluation Results
|
||||
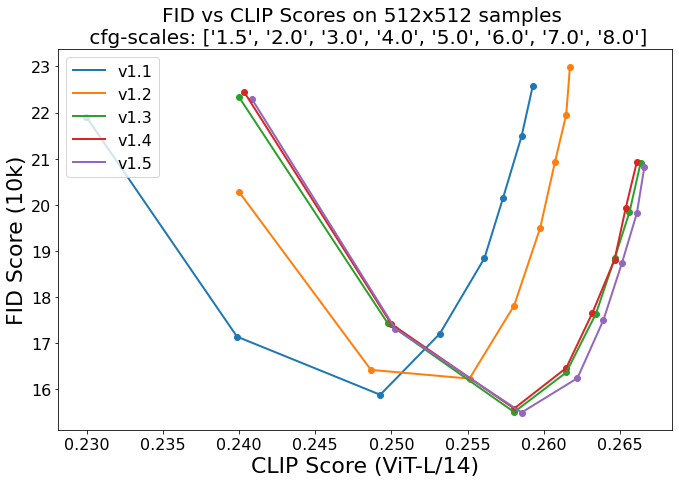
Evaluations with different classifier-free guidance scales (1.5, 2.0, 3.0, 4.0,
|
||||
5.0, 6.0, 7.0, 8.0) and 50 PNDM/PLMS sampling
|
||||
steps show the relative improvements of the checkpoints:
|
||||
|
||||
|
||||
|
||||
Evaluated using 50 PLMS steps and 10000 random prompts from the COCO2017 validation set, evaluated at 512x512 resolution. Not optimized for FID scores.
|
||||
## Environmental Impact
|
||||
|
||||
**Stable Diffusion v1** **Estimated Emissions**
|
||||
Based on that information, we estimate the following CO2 emissions using the [Machine Learning Impact calculator](https://mlco2.github.io/impact#compute) presented in [Lacoste et al. (2019)](https://arxiv.org/abs/1910.09700). The hardware, runtime, cloud provider, and compute region were utilized to estimate the carbon impact.
|
||||
|
||||
- **Hardware Type:** A100 PCIe 40GB
|
||||
- **Hours used:** 150000
|
||||
- **Cloud Provider:** AWS
|
||||
- **Compute Region:** US-east
|
||||
- **Carbon Emitted (Power consumption x Time x Carbon produced based on location of power grid):** 11250 kg CO2 eq.
|
||||
|
||||
|
||||
## Citation
|
||||
|
||||
```bibtex
|
||||
@InProceedings{Rombach_2022_CVPR,
|
||||
author = {Rombach, Robin and Blattmann, Andreas and Lorenz, Dominik and Esser, Patrick and Ommer, Bj\"orn},
|
||||
title = {High-Resolution Image Synthesis With Latent Diffusion Models},
|
||||
booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
|
||||
month = {June},
|
||||
year = {2022},
|
||||
pages = {10684-10695}
|
||||
}
|
||||
```
|
||||
|
||||
*This model card was written by: Robin Rombach and Patrick Esser and is based on the [DALL-E Mini model card](https://huggingface.co/dalle-mini/dalle-mini).*
|
||||
+20
@@ -0,0 +1,20 @@
|
||||
{
|
||||
"crop_size": 224,
|
||||
"do_center_crop": true,
|
||||
"do_convert_rgb": true,
|
||||
"do_normalize": true,
|
||||
"do_resize": true,
|
||||
"feature_extractor_type": "CLIPFeatureExtractor",
|
||||
"image_mean": [
|
||||
0.48145466,
|
||||
0.4578275,
|
||||
0.40821073
|
||||
],
|
||||
"image_std": [
|
||||
0.26862954,
|
||||
0.26130258,
|
||||
0.27577711
|
||||
],
|
||||
"resample": 3,
|
||||
"size": 224
|
||||
}
|
||||
@@ -0,0 +1,32 @@
|
||||
{
|
||||
"_class_name": "StableDiffusionPipeline",
|
||||
"_diffusers_version": "0.6.0",
|
||||
"feature_extractor": [
|
||||
"transformers",
|
||||
"CLIPImageProcessor"
|
||||
],
|
||||
"safety_checker": [
|
||||
"stable_diffusion",
|
||||
"StableDiffusionSafetyChecker"
|
||||
],
|
||||
"scheduler": [
|
||||
"diffusers",
|
||||
"PNDMScheduler"
|
||||
],
|
||||
"text_encoder": [
|
||||
"transformers",
|
||||
"CLIPTextModel"
|
||||
],
|
||||
"tokenizer": [
|
||||
"transformers",
|
||||
"CLIPTokenizer"
|
||||
],
|
||||
"unet": [
|
||||
"diffusers",
|
||||
"UNet2DConditionModel"
|
||||
],
|
||||
"vae": [
|
||||
"diffusers",
|
||||
"AutoencoderKL"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,175 @@
|
||||
{
|
||||
"_commit_hash": "4bb648a606ef040e7685bde262611766a5fdd67b",
|
||||
"_name_or_path": "CompVis/stable-diffusion-safety-checker",
|
||||
"architectures": [
|
||||
"StableDiffusionSafetyChecker"
|
||||
],
|
||||
"initializer_factor": 1.0,
|
||||
"logit_scale_init_value": 2.6592,
|
||||
"model_type": "clip",
|
||||
"projection_dim": 768,
|
||||
"text_config": {
|
||||
"_name_or_path": "",
|
||||
"add_cross_attention": false,
|
||||
"architectures": null,
|
||||
"attention_dropout": 0.0,
|
||||
"bad_words_ids": null,
|
||||
"bos_token_id": 0,
|
||||
"chunk_size_feed_forward": 0,
|
||||
"cross_attention_hidden_size": null,
|
||||
"decoder_start_token_id": null,
|
||||
"diversity_penalty": 0.0,
|
||||
"do_sample": false,
|
||||
"dropout": 0.0,
|
||||
"early_stopping": false,
|
||||
"encoder_no_repeat_ngram_size": 0,
|
||||
"eos_token_id": 2,
|
||||
"exponential_decay_length_penalty": null,
|
||||
"finetuning_task": null,
|
||||
"forced_bos_token_id": null,
|
||||
"forced_eos_token_id": null,
|
||||
"hidden_act": "quick_gelu",
|
||||
"hidden_size": 768,
|
||||
"id2label": {
|
||||
"0": "LABEL_0",
|
||||
"1": "LABEL_1"
|
||||
},
|
||||
"initializer_factor": 1.0,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 3072,
|
||||
"is_decoder": false,
|
||||
"is_encoder_decoder": false,
|
||||
"label2id": {
|
||||
"LABEL_0": 0,
|
||||
"LABEL_1": 1
|
||||
},
|
||||
"layer_norm_eps": 1e-05,
|
||||
"length_penalty": 1.0,
|
||||
"max_length": 20,
|
||||
"max_position_embeddings": 77,
|
||||
"min_length": 0,
|
||||
"model_type": "clip_text_model",
|
||||
"no_repeat_ngram_size": 0,
|
||||
"num_attention_heads": 12,
|
||||
"num_beam_groups": 1,
|
||||
"num_beams": 1,
|
||||
"num_hidden_layers": 12,
|
||||
"num_return_sequences": 1,
|
||||
"output_attentions": false,
|
||||
"output_hidden_states": false,
|
||||
"output_scores": false,
|
||||
"pad_token_id": 1,
|
||||
"prefix": null,
|
||||
"problem_type": null,
|
||||
"pruned_heads": {},
|
||||
"remove_invalid_values": false,
|
||||
"repetition_penalty": 1.0,
|
||||
"return_dict": true,
|
||||
"return_dict_in_generate": false,
|
||||
"sep_token_id": null,
|
||||
"task_specific_params": null,
|
||||
"temperature": 1.0,
|
||||
"tf_legacy_loss": false,
|
||||
"tie_encoder_decoder": false,
|
||||
"tie_word_embeddings": true,
|
||||
"tokenizer_class": null,
|
||||
"top_k": 50,
|
||||
"top_p": 1.0,
|
||||
"torch_dtype": null,
|
||||
"torchscript": false,
|
||||
"transformers_version": "4.22.0.dev0",
|
||||
"typical_p": 1.0,
|
||||
"use_bfloat16": false,
|
||||
"vocab_size": 49408
|
||||
},
|
||||
"text_config_dict": {
|
||||
"hidden_size": 768,
|
||||
"intermediate_size": 3072,
|
||||
"num_attention_heads": 12,
|
||||
"num_hidden_layers": 12
|
||||
},
|
||||
"torch_dtype": "float32",
|
||||
"transformers_version": null,
|
||||
"vision_config": {
|
||||
"_name_or_path": "",
|
||||
"add_cross_attention": false,
|
||||
"architectures": null,
|
||||
"attention_dropout": 0.0,
|
||||
"bad_words_ids": null,
|
||||
"bos_token_id": null,
|
||||
"chunk_size_feed_forward": 0,
|
||||
"cross_attention_hidden_size": null,
|
||||
"decoder_start_token_id": null,
|
||||
"diversity_penalty": 0.0,
|
||||
"do_sample": false,
|
||||
"dropout": 0.0,
|
||||
"early_stopping": false,
|
||||
"encoder_no_repeat_ngram_size": 0,
|
||||
"eos_token_id": null,
|
||||
"exponential_decay_length_penalty": null,
|
||||
"finetuning_task": null,
|
||||
"forced_bos_token_id": null,
|
||||
"forced_eos_token_id": null,
|
||||
"hidden_act": "quick_gelu",
|
||||
"hidden_size": 1024,
|
||||
"id2label": {
|
||||
"0": "LABEL_0",
|
||||
"1": "LABEL_1"
|
||||
},
|
||||
"image_size": 224,
|
||||
"initializer_factor": 1.0,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 4096,
|
||||
"is_decoder": false,
|
||||
"is_encoder_decoder": false,
|
||||
"label2id": {
|
||||
"LABEL_0": 0,
|
||||
"LABEL_1": 1
|
||||
},
|
||||
"layer_norm_eps": 1e-05,
|
||||
"length_penalty": 1.0,
|
||||
"max_length": 20,
|
||||
"min_length": 0,
|
||||
"model_type": "clip_vision_model",
|
||||
"no_repeat_ngram_size": 0,
|
||||
"num_attention_heads": 16,
|
||||
"num_beam_groups": 1,
|
||||
"num_beams": 1,
|
||||
"num_channels": 3,
|
||||
"num_hidden_layers": 24,
|
||||
"num_return_sequences": 1,
|
||||
"output_attentions": false,
|
||||
"output_hidden_states": false,
|
||||
"output_scores": false,
|
||||
"pad_token_id": null,
|
||||
"patch_size": 14,
|
||||
"prefix": null,
|
||||
"problem_type": null,
|
||||
"pruned_heads": {},
|
||||
"remove_invalid_values": false,
|
||||
"repetition_penalty": 1.0,
|
||||
"return_dict": true,
|
||||
"return_dict_in_generate": false,
|
||||
"sep_token_id": null,
|
||||
"task_specific_params": null,
|
||||
"temperature": 1.0,
|
||||
"tf_legacy_loss": false,
|
||||
"tie_encoder_decoder": false,
|
||||
"tie_word_embeddings": true,
|
||||
"tokenizer_class": null,
|
||||
"top_k": 50,
|
||||
"top_p": 1.0,
|
||||
"torch_dtype": null,
|
||||
"torchscript": false,
|
||||
"transformers_version": "4.22.0.dev0",
|
||||
"typical_p": 1.0,
|
||||
"use_bfloat16": false
|
||||
},
|
||||
"vision_config_dict": {
|
||||
"hidden_size": 1024,
|
||||
"intermediate_size": 4096,
|
||||
"num_attention_heads": 16,
|
||||
"num_hidden_layers": 24,
|
||||
"patch_size": 14
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,13 @@
|
||||
{
|
||||
"_class_name": "PNDMScheduler",
|
||||
"_diffusers_version": "0.6.0",
|
||||
"beta_end": 0.012,
|
||||
"beta_schedule": "scaled_linear",
|
||||
"beta_start": 0.00085,
|
||||
"num_train_timesteps": 1000,
|
||||
"set_alpha_to_one": false,
|
||||
"skip_prk_steps": true,
|
||||
"steps_offset": 1,
|
||||
"trained_betas": null,
|
||||
"clip_sample": false
|
||||
}
|
||||
@@ -0,0 +1,25 @@
|
||||
{
|
||||
"_name_or_path": "openai/clip-vit-large-patch14",
|
||||
"architectures": [
|
||||
"CLIPTextModel"
|
||||
],
|
||||
"attention_dropout": 0.0,
|
||||
"bos_token_id": 0,
|
||||
"dropout": 0.0,
|
||||
"eos_token_id": 2,
|
||||
"hidden_act": "quick_gelu",
|
||||
"hidden_size": 768,
|
||||
"initializer_factor": 1.0,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 3072,
|
||||
"layer_norm_eps": 1e-05,
|
||||
"max_position_embeddings": 77,
|
||||
"model_type": "clip_text_model",
|
||||
"num_attention_heads": 12,
|
||||
"num_hidden_layers": 12,
|
||||
"pad_token_id": 1,
|
||||
"projection_dim": 768,
|
||||
"torch_dtype": "float32",
|
||||
"transformers_version": "4.22.0.dev0",
|
||||
"vocab_size": 49408
|
||||
}
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,24 @@
|
||||
{
|
||||
"bos_token": {
|
||||
"content": "<|startoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"eos_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"pad_token": "<|endoftext|>",
|
||||
"unk_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,34 @@
|
||||
{
|
||||
"add_prefix_space": false,
|
||||
"bos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|startoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"do_lower_case": true,
|
||||
"eos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"errors": "replace",
|
||||
"model_max_length": 77,
|
||||
"name_or_path": "openai/clip-vit-large-patch14",
|
||||
"pad_token": "<|endoftext|>",
|
||||
"special_tokens_map_file": "./special_tokens_map.json",
|
||||
"tokenizer_class": "CLIPTokenizer",
|
||||
"unk_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,36 @@
|
||||
{
|
||||
"_class_name": "UNet2DConditionModel",
|
||||
"_diffusers_version": "0.6.0",
|
||||
"act_fn": "silu",
|
||||
"attention_head_dim": 8,
|
||||
"block_out_channels": [
|
||||
320,
|
||||
640,
|
||||
1280,
|
||||
1280
|
||||
],
|
||||
"center_input_sample": false,
|
||||
"cross_attention_dim": 768,
|
||||
"down_block_types": [
|
||||
"CrossAttnDownBlock2D",
|
||||
"CrossAttnDownBlock2D",
|
||||
"CrossAttnDownBlock2D",
|
||||
"DownBlock2D"
|
||||
],
|
||||
"downsample_padding": 1,
|
||||
"flip_sin_to_cos": true,
|
||||
"freq_shift": 0,
|
||||
"in_channels": 4,
|
||||
"layers_per_block": 2,
|
||||
"mid_block_scale_factor": 1,
|
||||
"norm_eps": 1e-05,
|
||||
"norm_num_groups": 32,
|
||||
"out_channels": 4,
|
||||
"sample_size": 64,
|
||||
"up_block_types": [
|
||||
"UpBlock2D",
|
||||
"CrossAttnUpBlock2D",
|
||||
"CrossAttnUpBlock2D",
|
||||
"CrossAttnUpBlock2D"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,70 @@
|
||||
model:
|
||||
base_learning_rate: 1.0e-04
|
||||
target: ldm.models.diffusion.ddpm.LatentDiffusion
|
||||
params:
|
||||
linear_start: 0.00085
|
||||
linear_end: 0.0120
|
||||
num_timesteps_cond: 1
|
||||
log_every_t: 200
|
||||
timesteps: 1000
|
||||
first_stage_key: "jpg"
|
||||
cond_stage_key: "txt"
|
||||
image_size: 64
|
||||
channels: 4
|
||||
cond_stage_trainable: false # Note: different from the one we trained before
|
||||
conditioning_key: crossattn
|
||||
monitor: val/loss_simple_ema
|
||||
scale_factor: 0.18215
|
||||
use_ema: False
|
||||
|
||||
scheduler_config: # 10000 warmup steps
|
||||
target: ldm.lr_scheduler.LambdaLinearScheduler
|
||||
params:
|
||||
warm_up_steps: [ 10000 ]
|
||||
cycle_lengths: [ 10000000000000 ] # incredibly large number to prevent corner cases
|
||||
f_start: [ 1.e-6 ]
|
||||
f_max: [ 1. ]
|
||||
f_min: [ 1. ]
|
||||
|
||||
unet_config:
|
||||
target: ldm.modules.diffusionmodules.openaimodel.UNetModel
|
||||
params:
|
||||
image_size: 32 # unused
|
||||
in_channels: 4
|
||||
out_channels: 4
|
||||
model_channels: 320
|
||||
attention_resolutions: [ 4, 2, 1 ]
|
||||
num_res_blocks: 2
|
||||
channel_mult: [ 1, 2, 4, 4 ]
|
||||
num_heads: 8
|
||||
use_spatial_transformer: True
|
||||
transformer_depth: 1
|
||||
context_dim: 768
|
||||
use_checkpoint: True
|
||||
legacy: False
|
||||
|
||||
first_stage_config:
|
||||
target: ldm.models.autoencoder.AutoencoderKL
|
||||
params:
|
||||
embed_dim: 4
|
||||
monitor: val/rec_loss
|
||||
ddconfig:
|
||||
double_z: true
|
||||
z_channels: 4
|
||||
resolution: 256
|
||||
in_channels: 3
|
||||
out_ch: 3
|
||||
ch: 128
|
||||
ch_mult:
|
||||
- 1
|
||||
- 2
|
||||
- 4
|
||||
- 4
|
||||
num_res_blocks: 2
|
||||
attn_resolutions: []
|
||||
dropout: 0.0
|
||||
lossconfig:
|
||||
target: torch.nn.Identity
|
||||
|
||||
cond_stage_config:
|
||||
target: ldm.modules.encoders.modules.FrozenCLIPEmbedder
|
||||
@@ -0,0 +1,29 @@
|
||||
{
|
||||
"_class_name": "AutoencoderKL",
|
||||
"_diffusers_version": "0.6.0",
|
||||
"act_fn": "silu",
|
||||
"block_out_channels": [
|
||||
128,
|
||||
256,
|
||||
512,
|
||||
512
|
||||
],
|
||||
"down_block_types": [
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D"
|
||||
],
|
||||
"in_channels": 3,
|
||||
"latent_channels": 4,
|
||||
"layers_per_block": 2,
|
||||
"norm_num_groups": 32,
|
||||
"out_channels": 3,
|
||||
"sample_size": 512,
|
||||
"up_block_types": [
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,36 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
01.png filter=lfs diff=lfs merge=lfs -text
|
||||
@@ -0,0 +1,60 @@
|
||||
Copyright (c) 2023 Stability AI
|
||||
CreativeML Open RAIL++-M License dated July 26, 2023
|
||||
|
||||
Section I: PREAMBLE
|
||||
Multimodal generative models are being widely adopted and used, and have the potential to transform the way artists, among other individuals, conceive and benefit from AI or ML technologies as a tool for content creation.
|
||||
Notwithstanding the current and potential benefits that these artifacts can bring to society at large, there are also concerns about potential misuses of them, either due to their technical limitations or ethical considerations.
|
||||
In short, this license strives for both the open and responsible downstream use of the accompanying model. When it comes to the open character, we took inspiration from open source permissive licenses regarding the grant of IP rights. Referring to the downstream responsible use, we added use-based restrictions not permitting the use of the model in very specific scenarios, in order for the licensor to be able to enforce the license in case potential misuses of the Model may occur. At the same time, we strive to promote open and responsible research on generative models for art and content generation.
|
||||
Even though downstream derivative versions of the model could be released under different licensing terms, the latter will always have to include - at minimum - the same use-based restrictions as the ones in the original license (this license). We believe in the intersection between open and responsible AI development; thus, this agreement aims to strike a balance between both in order to enable responsible open-science in the field of AI.
|
||||
This CreativeML Open RAIL++-M License governs the use of the model (and its derivatives) and is informed by the model card associated with the model.
|
||||
NOW THEREFORE, You and Licensor agree as follows:
|
||||
Definitions
|
||||
"License" means the terms and conditions for use, reproduction, and Distribution as defined in this document.
|
||||
"Data" means a collection of information and/or content extracted from the dataset used with the Model, including to train, pretrain, or otherwise evaluate the Model. The Data is not licensed under this License.
|
||||
"Output" means the results of operating a Model as embodied in informational content resulting therefrom.
|
||||
"Model" means any accompanying machine-learning based assemblies (including checkpoints), consisting of learnt weights, parameters (including optimizer states), corresponding to the model architecture as embodied in the Complementary Material, that have been trained or tuned, in whole or in part on the Data, using the Complementary Material.
|
||||
"Derivatives of the Model" means all modifications to the Model, works based on the Model, or any other model which is created or initialized by transfer of patterns of the weights, parameters, activations or output of the Model, to the other model, in order to cause the other model to perform similarly to the Model, including - but not limited to - distillation methods entailing the use of intermediate data representations or methods based on the generation of synthetic data by the Model for training the other model.
|
||||
"Complementary Material" means the accompanying source code and scripts used to define, run, load, benchmark or evaluate the Model, and used to prepare data for training or evaluation, if any. This includes any accompanying documentation, tutorials, examples, etc, if any.
|
||||
"Distribution" means any transmission, reproduction, publication or other sharing of the Model or Derivatives of the Model to a third party, including providing the Model as a hosted service made available by electronic or other remote means - e.g. API-based or web access.
|
||||
"Licensor" means the copyright owner or entity authorized by the copyright owner that is granting the License, including the persons or entities that may have rights in the Model and/or distributing the Model.
|
||||
"You" (or "Your") means an individual or Legal Entity exercising permissions granted by this License and/or making use of the Model for whichever purpose and in any field of use, including usage of the Model in an end-use application - e.g. chatbot, translator, image generator.
|
||||
"Third Parties" means individuals or legal entities that are not under common control with Licensor or You.
|
||||
"Contribution" means any work of authorship, including the original version of the Model and any modifications or additions to that Model or Derivatives of the Model thereof, that is intentionally submitted to Licensor for inclusion in the Model by the copyright owner or by an individual or Legal Entity authorized to submit on behalf of the copyright owner. For the purposes of this definition, "submitted" means any form of electronic, verbal, or written communication sent to the Licensor or its representatives, including but not limited to communication on electronic mailing lists, source code control systems, and issue tracking systems that are managed by, or on behalf of, the Licensor for the purpose of discussing and improving the Model, but excluding communication that is conspicuously marked or otherwise designated in writing by the copyright owner as "Not a Contribution."
|
||||
"Contributor" means Licensor and any individual or Legal Entity on behalf of whom a Contribution has been received by Licensor and subsequently incorporated within the Model.
|
||||
|
||||
Section II: INTELLECTUAL PROPERTY RIGHTS
|
||||
Both copyright and patent grants apply to the Model, Derivatives of the Model and Complementary Material. The Model and Derivatives of the Model are subject to additional terms as described in
|
||||
|
||||
Section III.
|
||||
Grant of Copyright License. Subject to the terms and conditions of this License, each Contributor hereby grants to You a perpetual, worldwide, non-exclusive, no-charge, royalty-free, irrevocable copyright license to reproduce, prepare, publicly display, publicly perform, sublicense, and distribute the Complementary Material, the Model, and Derivatives of the Model.
|
||||
Grant of Patent License. Subject to the terms and conditions of this License and where and as applicable, each Contributor hereby grants to You a perpetual, worldwide, non-exclusive, no-charge, royalty-free, irrevocable (except as stated in this paragraph) patent license to make, have made, use, offer to sell, sell, import, and otherwise transfer the Model and the Complementary Material, where such license applies only to those patent claims licensable by such Contributor that are necessarily infringed by their Contribution(s) alone or by combination of their Contribution(s) with the Model to which such Contribution(s) was submitted. If You institute patent litigation against any entity (including a cross-claim or counterclaim in a lawsuit) alleging that the Model and/or Complementary Material or a Contribution incorporated within the Model and/or Complementary Material constitutes direct or contributory patent infringement, then any patent licenses granted to You under this License for the Model and/or Work shall terminate as of the date such litigation is asserted or filed.
|
||||
Section III: CONDITIONS OF USAGE, DISTRIBUTION AND REDISTRIBUTION
|
||||
Distribution and Redistribution. You may host for Third Party remote access purposes (e.g. software-as-a-service), reproduce and distribute copies of the Model or Derivatives of the Model thereof in any medium, with or without modifications, provided that You meet the following conditions: Use-based restrictions as referenced in paragraph 5 MUST be included as an enforceable provision by You in any type of legal agreement (e.g. a license) governing the use and/or distribution of the Model or Derivatives of the Model, and You shall give notice to subsequent users You Distribute to, that the Model or Derivatives of the Model are subject to paragraph 5. This provision does not apply to the use of Complementary Material. You must give any Third Party recipients of the Model or Derivatives of the Model a copy of this License; You must cause any modified files to carry prominent notices stating that You changed the files; You must retain all copyright, patent, trademark, and attribution notices excluding those notices that do not pertain to any part of the Model, Derivatives of the Model. You may add Your own copyright statement to Your modifications and may provide additional or different license terms and conditions - respecting paragraph 4.a. - for use, reproduction, or Distribution of Your modifications, or for any such Derivatives of the Model as a whole, provided Your use, reproduction, and Distribution of the Model otherwise complies with the conditions stated in this License.
|
||||
Use-based restrictions. The restrictions set forth in Attachment A are considered Use-based restrictions. Therefore You cannot use the Model and the Derivatives of the Model for the specified restricted uses. You may use the Model subject to this License, including only for lawful purposes and in accordance with the License. Use may include creating any content with, finetuning, updating, running, training, evaluating and/or reparametrizing the Model. You shall require all of Your users who use the Model or a Derivative of the Model to comply with the terms of this paragraph (paragraph 5).
|
||||
The Output You Generate. Except as set forth herein, Licensor claims no rights in the Output You generate using the Model. You are accountable for the Output you generate and its subsequent uses. No use of the output can contravene any provision as stated in the License.
|
||||
|
||||
Section IV: OTHER PROVISIONS
|
||||
Updates and Runtime Restrictions. To the maximum extent permitted by law, Licensor reserves the right to restrict (remotely or otherwise) usage of the Model in violation of this License.
|
||||
Trademarks and related. Nothing in this License permits You to make use of Licensors’ trademarks, trade names, logos or to otherwise suggest endorsement or misrepresent the relationship between the parties; and any rights not expressly granted herein are reserved by the Licensors.
|
||||
Disclaimer of Warranty. Unless required by applicable law or agreed to in writing, Licensor provides the Model and the Complementary Material (and each Contributor provides its Contributions) on an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied, including, without limitation, any warranties or conditions of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A PARTICULAR PURPOSE. You are solely responsible for determining the appropriateness of using or redistributing the Model, Derivatives of the Model, and the Complementary Material and assume any risks associated with Your exercise of permissions under this License.
|
||||
Limitation of Liability. In no event and under no legal theory, whether in tort (including negligence), contract, or otherwise, unless required by applicable law (such as deliberate and grossly negligent acts) or agreed to in writing, shall any Contributor be liable to You for damages, including any direct, indirect, special, incidental, or consequential damages of any character arising as a result of this License or out of the use or inability to use the Model and the Complementary Material (including but not limited to damages for loss of goodwill, work stoppage, computer failure or malfunction, or any and all other commercial damages or losses), even if such Contributor has been advised of the possibility of such damages.
|
||||
Accepting Warranty or Additional Liability. While redistributing the Model, Derivatives of the Model and the Complementary Material thereof, You may choose to offer, and charge a fee for, acceptance of support, warranty, indemnity, or other liability obligations and/or rights consistent with this License. However, in accepting such obligations, You may act only on Your own behalf and on Your sole responsibility, not on behalf of any other Contributor, and only if You agree to indemnify, defend, and hold each Contributor harmless for any liability incurred by, or claims asserted against, such Contributor by reason of your accepting any such warranty or additional liability.
|
||||
If any provision of this License is held to be invalid, illegal or unenforceable, the remaining provisions shall be unaffected thereby and remain valid as if such provision had not been set forth herein.
|
||||
|
||||
END OF TERMS AND CONDITIONS
|
||||
|
||||
Attachment A
|
||||
Use Restrictions
|
||||
You agree not to use the Model or Derivatives of the Model:
|
||||
In any way that violates any applicable national, federal, state, local or international law or regulation;
|
||||
For the purpose of exploiting, harming or attempting to exploit or harm minors in any way;
|
||||
To generate or disseminate verifiably false information and/or content with the purpose of harming others;
|
||||
To generate or disseminate personal identifiable information that can be used to harm an individual;
|
||||
To defame, disparage or otherwise harass others;
|
||||
For fully automated decision making that adversely impacts an individual’s legal rights or otherwise creates or modifies a binding, enforceable obligation;
|
||||
For any use intended to or which has the effect of discriminating against or harming individuals or groups based on online or offline social behavior or known or predicted personal or personality characteristics;
|
||||
To exploit any of the vulnerabilities of a specific group of persons based on their age, social, physical or mental characteristics, in order to materially distort the behavior of a person pertaining to that group in a manner that causes or is likely to cause that person or another person physical or psychological harm;
|
||||
For any use intended to or which has the effect of discriminating against individuals or groups based on legally protected characteristics or categories;
|
||||
To provide medical advice and medical results interpretation;
|
||||
To generate or disseminate information for the purpose to be used for administration of justice, law enforcement, immigration or asylum processes, such as predicting an individual will commit fraud/crime commitment (e.g. by text profiling, drawing causal relationships between assertions made in documents, indiscriminate and arbitrarily-targeted use).
|
||||
|
||||
@@ -0,0 +1,215 @@
|
||||
---
|
||||
license: openrail++
|
||||
tags:
|
||||
- text-to-image
|
||||
- stable-diffusion
|
||||
---
|
||||
# SD-XL 1.0-base Model Card
|
||||

|
||||
|
||||
## Model
|
||||
|
||||

|
||||
|
||||
[SDXL](https://arxiv.org/abs/2307.01952) consists of an [ensemble of experts](https://arxiv.org/abs/2211.01324) pipeline for latent diffusion:
|
||||
In a first step, the base model is used to generate (noisy) latents,
|
||||
which are then further processed with a refinement model (available here: https://huggingface.co/stabilityai/stable-diffusion-xl-refiner-1.0/) specialized for the final denoising steps.
|
||||
Note that the base model can be used as a standalone module.
|
||||
|
||||
Alternatively, we can use a two-stage pipeline as follows:
|
||||
First, the base model is used to generate latents of the desired output size.
|
||||
In the second step, we use a specialized high-resolution model and apply a technique called SDEdit (https://arxiv.org/abs/2108.01073, also known as "img2img")
|
||||
to the latents generated in the first step, using the same prompt. This technique is slightly slower than the first one, as it requires more function evaluations.
|
||||
|
||||
Source code is available at https://github.com/Stability-AI/generative-models .
|
||||
|
||||
### Model Description
|
||||
|
||||
- **Developed by:** Stability AI
|
||||
- **Model type:** Diffusion-based text-to-image generative model
|
||||
- **License:** [CreativeML Open RAIL++-M License](https://huggingface.co/stabilityai/stable-diffusion-xl-base-1.0/blob/main/LICENSE.md)
|
||||
- **Model Description:** This is a model that can be used to generate and modify images based on text prompts. It is a [Latent Diffusion Model](https://arxiv.org/abs/2112.10752) that uses two fixed, pretrained text encoders ([OpenCLIP-ViT/G](https://github.com/mlfoundations/open_clip) and [CLIP-ViT/L](https://github.com/openai/CLIP/tree/main)).
|
||||
- **Resources for more information:** Check out our [GitHub Repository](https://github.com/Stability-AI/generative-models) and the [SDXL report on arXiv](https://arxiv.org/abs/2307.01952).
|
||||
|
||||
### Model Sources
|
||||
|
||||
For research purposes, we recommend our `generative-models` Github repository (https://github.com/Stability-AI/generative-models), which implements the most popular diffusion frameworks (both training and inference) and for which new functionalities like distillation will be added over time.
|
||||
[Clipdrop](https://clipdrop.co/stable-diffusion) provides free SDXL inference.
|
||||
|
||||
- **Repository:** https://github.com/Stability-AI/generative-models
|
||||
- **Demo:** https://clipdrop.co/stable-diffusion
|
||||
|
||||
|
||||
## Evaluation
|
||||

|
||||
The chart above evaluates user preference for SDXL (with and without refinement) over SDXL 0.9 and Stable Diffusion 1.5 and 2.1.
|
||||
The SDXL base model performs significantly better than the previous variants, and the model combined with the refinement module achieves the best overall performance.
|
||||
|
||||
|
||||
### 🧨 Diffusers
|
||||
|
||||
Make sure to upgrade diffusers to >= 0.19.0:
|
||||
```
|
||||
pip install diffusers --upgrade
|
||||
```
|
||||
|
||||
In addition make sure to install `transformers`, `safetensors`, `accelerate` as well as the invisible watermark:
|
||||
```
|
||||
pip install invisible_watermark transformers accelerate safetensors
|
||||
```
|
||||
|
||||
To just use the base model, you can run:
|
||||
|
||||
```py
|
||||
from diffusers import DiffusionPipeline
|
||||
import torch
|
||||
|
||||
pipe = DiffusionPipeline.from_pretrained("stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.float16, use_safetensors=True, variant="fp16")
|
||||
pipe.to("cuda")
|
||||
|
||||
# if using torch < 2.0
|
||||
# pipe.enable_xformers_memory_efficient_attention()
|
||||
|
||||
prompt = "An astronaut riding a green horse"
|
||||
|
||||
images = pipe(prompt=prompt).images[0]
|
||||
```
|
||||
|
||||
To use the whole base + refiner pipeline as an ensemble of experts you can run:
|
||||
|
||||
```py
|
||||
from diffusers import DiffusionPipeline
|
||||
import torch
|
||||
|
||||
# load both base & refiner
|
||||
base = DiffusionPipeline.from_pretrained(
|
||||
"stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.float16, variant="fp16", use_safetensors=True
|
||||
)
|
||||
base.to("cuda")
|
||||
refiner = DiffusionPipeline.from_pretrained(
|
||||
"stabilityai/stable-diffusion-xl-refiner-1.0",
|
||||
text_encoder_2=base.text_encoder_2,
|
||||
vae=base.vae,
|
||||
torch_dtype=torch.float16,
|
||||
use_safetensors=True,
|
||||
variant="fp16",
|
||||
)
|
||||
refiner.to("cuda")
|
||||
|
||||
# Define how many steps and what % of steps to be run on each experts (80/20) here
|
||||
n_steps = 40
|
||||
high_noise_frac = 0.8
|
||||
|
||||
prompt = "A majestic lion jumping from a big stone at night"
|
||||
|
||||
# run both experts
|
||||
image = base(
|
||||
prompt=prompt,
|
||||
num_inference_steps=n_steps,
|
||||
denoising_end=high_noise_frac,
|
||||
output_type="latent",
|
||||
).images
|
||||
image = refiner(
|
||||
prompt=prompt,
|
||||
num_inference_steps=n_steps,
|
||||
denoising_start=high_noise_frac,
|
||||
image=image,
|
||||
).images[0]
|
||||
```
|
||||
|
||||
When using `torch >= 2.0`, you can improve the inference speed by 20-30% with torch.compile. Simple wrap the unet with torch compile before running the pipeline:
|
||||
```py
|
||||
pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True)
|
||||
```
|
||||
|
||||
If you are limited by GPU VRAM, you can enable *cpu offloading* by calling `pipe.enable_model_cpu_offload`
|
||||
instead of `.to("cuda")`:
|
||||
|
||||
```diff
|
||||
- pipe.to("cuda")
|
||||
+ pipe.enable_model_cpu_offload()
|
||||
```
|
||||
|
||||
For more information on how to use Stable Diffusion XL with `diffusers`, please have a look at [the Stable Diffusion XL Docs](https://huggingface.co/docs/diffusers/api/pipelines/stable_diffusion/stable_diffusion_xl).
|
||||
|
||||
### Optimum
|
||||
[Optimum](https://github.com/huggingface/optimum) provides a Stable Diffusion pipeline compatible with both [OpenVINO](https://docs.openvino.ai/latest/index.html) and [ONNX Runtime](https://onnxruntime.ai/).
|
||||
|
||||
#### OpenVINO
|
||||
|
||||
To install Optimum with the dependencies required for OpenVINO :
|
||||
|
||||
```bash
|
||||
pip install optimum[openvino]
|
||||
```
|
||||
|
||||
To load an OpenVINO model and run inference with OpenVINO Runtime, you need to replace `StableDiffusionXLPipeline` with Optimum `OVStableDiffusionXLPipeline`. In case you want to load a PyTorch model and convert it to the OpenVINO format on-the-fly, you can set `export=True`.
|
||||
|
||||
```diff
|
||||
- from diffusers import StableDiffusionXLPipeline
|
||||
+ from optimum.intel import OVStableDiffusionXLPipeline
|
||||
|
||||
model_id = "stabilityai/stable-diffusion-xl-base-1.0"
|
||||
- pipeline = StableDiffusionXLPipeline.from_pretrained(model_id)
|
||||
+ pipeline = OVStableDiffusionXLPipeline.from_pretrained(model_id)
|
||||
prompt = "A majestic lion jumping from a big stone at night"
|
||||
image = pipeline(prompt).images[0]
|
||||
```
|
||||
|
||||
You can find more examples (such as static reshaping and model compilation) in optimum [documentation](https://huggingface.co/docs/optimum/main/en/intel/inference#stable-diffusion-xl).
|
||||
|
||||
|
||||
#### ONNX
|
||||
|
||||
To install Optimum with the dependencies required for ONNX Runtime inference :
|
||||
|
||||
```bash
|
||||
pip install optimum[onnxruntime]
|
||||
```
|
||||
|
||||
To load an ONNX model and run inference with ONNX Runtime, you need to replace `StableDiffusionXLPipeline` with Optimum `ORTStableDiffusionXLPipeline`. In case you want to load a PyTorch model and convert it to the ONNX format on-the-fly, you can set `export=True`.
|
||||
|
||||
```diff
|
||||
- from diffusers import StableDiffusionXLPipeline
|
||||
+ from optimum.onnxruntime import ORTStableDiffusionXLPipeline
|
||||
|
||||
model_id = "stabilityai/stable-diffusion-xl-base-1.0"
|
||||
- pipeline = StableDiffusionXLPipeline.from_pretrained(model_id)
|
||||
+ pipeline = ORTStableDiffusionXLPipeline.from_pretrained(model_id)
|
||||
prompt = "A majestic lion jumping from a big stone at night"
|
||||
image = pipeline(prompt).images[0]
|
||||
```
|
||||
|
||||
You can find more examples in optimum [documentation](https://huggingface.co/docs/optimum/main/en/onnxruntime/usage_guides/models#stable-diffusion-xl).
|
||||
|
||||
|
||||
## Uses
|
||||
|
||||
### Direct Use
|
||||
|
||||
The model is intended for research purposes only. Possible research areas and tasks include
|
||||
|
||||
- Generation of artworks and use in design and other artistic processes.
|
||||
- Applications in educational or creative tools.
|
||||
- Research on generative models.
|
||||
- Safe deployment of models which have the potential to generate harmful content.
|
||||
- Probing and understanding the limitations and biases of generative models.
|
||||
|
||||
Excluded uses are described below.
|
||||
|
||||
### Out-of-Scope Use
|
||||
|
||||
The model was not trained to be factual or true representations of people or events, and therefore using the model to generate such content is out-of-scope for the abilities of this model.
|
||||
|
||||
## Limitations and Bias
|
||||
|
||||
### Limitations
|
||||
|
||||
- The model does not achieve perfect photorealism
|
||||
- The model cannot render legible text
|
||||
- The model struggles with more difficult tasks which involve compositionality, such as rendering an image corresponding to “A red cube on top of a blue sphere”
|
||||
- Faces and people in general may not be generated properly.
|
||||
- The autoencoding part of the model is lossy.
|
||||
|
||||
### Bias
|
||||
While the capabilities of image generation models are impressive, they can also reinforce or exacerbate social biases.
|
||||
@@ -0,0 +1,34 @@
|
||||
{
|
||||
"_class_name": "StableDiffusionXLPipeline",
|
||||
"_diffusers_version": "0.19.0.dev0",
|
||||
"force_zeros_for_empty_prompt": true,
|
||||
"add_watermarker": null,
|
||||
"scheduler": [
|
||||
"diffusers",
|
||||
"EulerDiscreteScheduler"
|
||||
],
|
||||
"text_encoder": [
|
||||
"transformers",
|
||||
"CLIPTextModel"
|
||||
],
|
||||
"text_encoder_2": [
|
||||
"transformers",
|
||||
"CLIPTextModelWithProjection"
|
||||
],
|
||||
"tokenizer": [
|
||||
"transformers",
|
||||
"CLIPTokenizer"
|
||||
],
|
||||
"tokenizer_2": [
|
||||
"transformers",
|
||||
"CLIPTokenizer"
|
||||
],
|
||||
"unet": [
|
||||
"diffusers",
|
||||
"UNet2DConditionModel"
|
||||
],
|
||||
"vae": [
|
||||
"diffusers",
|
||||
"AutoencoderKL"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,18 @@
|
||||
{
|
||||
"_class_name": "EulerDiscreteScheduler",
|
||||
"_diffusers_version": "0.19.0.dev0",
|
||||
"beta_end": 0.012,
|
||||
"beta_schedule": "scaled_linear",
|
||||
"beta_start": 0.00085,
|
||||
"clip_sample": false,
|
||||
"interpolation_type": "linear",
|
||||
"num_train_timesteps": 1000,
|
||||
"prediction_type": "epsilon",
|
||||
"sample_max_value": 1.0,
|
||||
"set_alpha_to_one": false,
|
||||
"skip_prk_steps": true,
|
||||
"steps_offset": 1,
|
||||
"timestep_spacing": "leading",
|
||||
"trained_betas": null,
|
||||
"use_karras_sigmas": false
|
||||
}
|
||||
@@ -0,0 +1,24 @@
|
||||
{
|
||||
"architectures": [
|
||||
"CLIPTextModel"
|
||||
],
|
||||
"attention_dropout": 0.0,
|
||||
"bos_token_id": 0,
|
||||
"dropout": 0.0,
|
||||
"eos_token_id": 2,
|
||||
"hidden_act": "quick_gelu",
|
||||
"hidden_size": 768,
|
||||
"initializer_factor": 1.0,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 3072,
|
||||
"layer_norm_eps": 1e-05,
|
||||
"max_position_embeddings": 77,
|
||||
"model_type": "clip_text_model",
|
||||
"num_attention_heads": 12,
|
||||
"num_hidden_layers": 12,
|
||||
"pad_token_id": 1,
|
||||
"projection_dim": 768,
|
||||
"torch_dtype": "float16",
|
||||
"transformers_version": "4.32.0.dev0",
|
||||
"vocab_size": 49408
|
||||
}
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:ab5cf7327374d8c984f4e963564a329f92c9dad08dac9eee9b8dca86b912f1c9
|
||||
size 1057789
|
||||
@@ -0,0 +1,24 @@
|
||||
{
|
||||
"architectures": [
|
||||
"CLIPTextModelWithProjection"
|
||||
],
|
||||
"attention_dropout": 0.0,
|
||||
"bos_token_id": 0,
|
||||
"dropout": 0.0,
|
||||
"eos_token_id": 2,
|
||||
"hidden_act": "gelu",
|
||||
"hidden_size": 1280,
|
||||
"initializer_factor": 1.0,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 5120,
|
||||
"layer_norm_eps": 1e-05,
|
||||
"max_position_embeddings": 77,
|
||||
"model_type": "clip_text_model",
|
||||
"num_attention_heads": 20,
|
||||
"num_hidden_layers": 32,
|
||||
"pad_token_id": 1,
|
||||
"projection_dim": 1280,
|
||||
"torch_dtype": "float16",
|
||||
"transformers_version": "4.32.0.dev0",
|
||||
"vocab_size": 49408
|
||||
}
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:38f0a4ff68dd918b24908a264140c2ad0e057eca82616f75c17cbf4a099ad6ad
|
||||
size 2790191
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,24 @@
|
||||
{
|
||||
"bos_token": {
|
||||
"content": "<|startoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"eos_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"pad_token": "<|endoftext|>",
|
||||
"unk_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,33 @@
|
||||
{
|
||||
"add_prefix_space": false,
|
||||
"bos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|startoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"clean_up_tokenization_spaces": true,
|
||||
"do_lower_case": true,
|
||||
"eos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"errors": "replace",
|
||||
"model_max_length": 77,
|
||||
"pad_token": "<|endoftext|>",
|
||||
"tokenizer_class": "CLIPTokenizer",
|
||||
"unk_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
File diff suppressed because it is too large
Load Diff
File diff suppressed because it is too large
Load Diff
+24
@@ -0,0 +1,24 @@
|
||||
{
|
||||
"bos_token": {
|
||||
"content": "<|startoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"eos_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"pad_token": "!",
|
||||
"unk_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,33 @@
|
||||
{
|
||||
"add_prefix_space": false,
|
||||
"bos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|startoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"clean_up_tokenization_spaces": true,
|
||||
"do_lower_case": true,
|
||||
"eos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"errors": "replace",
|
||||
"model_max_length": 77,
|
||||
"pad_token": "!",
|
||||
"tokenizer_class": "CLIPTokenizer",
|
||||
"unk_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,69 @@
|
||||
{
|
||||
"_class_name": "UNet2DConditionModel",
|
||||
"_diffusers_version": "0.19.0.dev0",
|
||||
"act_fn": "silu",
|
||||
"addition_embed_type": "text_time",
|
||||
"addition_embed_type_num_heads": 64,
|
||||
"addition_time_embed_dim": 256,
|
||||
"attention_head_dim": [
|
||||
5,
|
||||
10,
|
||||
20
|
||||
],
|
||||
"block_out_channels": [
|
||||
320,
|
||||
640,
|
||||
1280
|
||||
],
|
||||
"center_input_sample": false,
|
||||
"class_embed_type": null,
|
||||
"class_embeddings_concat": false,
|
||||
"conv_in_kernel": 3,
|
||||
"conv_out_kernel": 3,
|
||||
"cross_attention_dim": 2048,
|
||||
"cross_attention_norm": null,
|
||||
"down_block_types": [
|
||||
"DownBlock2D",
|
||||
"CrossAttnDownBlock2D",
|
||||
"CrossAttnDownBlock2D"
|
||||
],
|
||||
"downsample_padding": 1,
|
||||
"dual_cross_attention": false,
|
||||
"encoder_hid_dim": null,
|
||||
"encoder_hid_dim_type": null,
|
||||
"flip_sin_to_cos": true,
|
||||
"freq_shift": 0,
|
||||
"in_channels": 4,
|
||||
"layers_per_block": 2,
|
||||
"mid_block_only_cross_attention": null,
|
||||
"mid_block_scale_factor": 1,
|
||||
"mid_block_type": "UNetMidBlock2DCrossAttn",
|
||||
"norm_eps": 1e-05,
|
||||
"norm_num_groups": 32,
|
||||
"num_attention_heads": null,
|
||||
"num_class_embeds": null,
|
||||
"only_cross_attention": false,
|
||||
"out_channels": 4,
|
||||
"projection_class_embeddings_input_dim": 2816,
|
||||
"resnet_out_scale_factor": 1.0,
|
||||
"resnet_skip_time_act": false,
|
||||
"resnet_time_scale_shift": "default",
|
||||
"sample_size": 128,
|
||||
"time_cond_proj_dim": null,
|
||||
"time_embedding_act_fn": null,
|
||||
"time_embedding_dim": null,
|
||||
"time_embedding_type": "positional",
|
||||
"timestep_post_act": null,
|
||||
"transformer_layers_per_block": [
|
||||
1,
|
||||
2,
|
||||
10
|
||||
],
|
||||
"up_block_types": [
|
||||
"CrossAttnUpBlock2D",
|
||||
"CrossAttnUpBlock2D",
|
||||
"UpBlock2D"
|
||||
],
|
||||
"upcast_attention": null,
|
||||
"use_linear_projection": true
|
||||
}
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:18955f96dffdba5612c4b554451f4ccc947c93e46df010173791654af4d0d7f6
|
||||
size 22577438
|
||||
@@ -0,0 +1,32 @@
|
||||
{
|
||||
"_class_name": "AutoencoderKL",
|
||||
"_diffusers_version": "0.20.0.dev0",
|
||||
"_name_or_path": "../sdxl-vae/",
|
||||
"act_fn": "silu",
|
||||
"block_out_channels": [
|
||||
128,
|
||||
256,
|
||||
512,
|
||||
512
|
||||
],
|
||||
"down_block_types": [
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D"
|
||||
],
|
||||
"force_upcast": true,
|
||||
"in_channels": 3,
|
||||
"latent_channels": 4,
|
||||
"layers_per_block": 2,
|
||||
"norm_num_groups": 32,
|
||||
"out_channels": 3,
|
||||
"sample_size": 1024,
|
||||
"scaling_factor": 0.13025,
|
||||
"up_block_types": [
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,31 @@
|
||||
{
|
||||
"_class_name": "AutoencoderKL",
|
||||
"_diffusers_version": "0.19.0.dev0",
|
||||
"act_fn": "silu",
|
||||
"block_out_channels": [
|
||||
128,
|
||||
256,
|
||||
512,
|
||||
512
|
||||
],
|
||||
"down_block_types": [
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D"
|
||||
],
|
||||
"force_upcast": true,
|
||||
"in_channels": 3,
|
||||
"latent_channels": 4,
|
||||
"layers_per_block": 2,
|
||||
"norm_num_groups": 32,
|
||||
"out_channels": 3,
|
||||
"sample_size": 1024,
|
||||
"scaling_factor": 0.13025,
|
||||
"up_block_types": [
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:dd61f43e981282b77ecaecf5fc5c842d504932bae78ac99ec581cee50978b423
|
||||
size 992181
|
||||
@@ -0,0 +1,31 @@
|
||||
{
|
||||
"_class_name": "AutoencoderKL",
|
||||
"_diffusers_version": "0.19.0.dev0",
|
||||
"act_fn": "silu",
|
||||
"block_out_channels": [
|
||||
128,
|
||||
256,
|
||||
512,
|
||||
512
|
||||
],
|
||||
"down_block_types": [
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D"
|
||||
],
|
||||
"force_upcast": true,
|
||||
"in_channels": 3,
|
||||
"latent_channels": 4,
|
||||
"layers_per_block": 2,
|
||||
"norm_num_groups": 32,
|
||||
"out_channels": 3,
|
||||
"sample_size": 1024,
|
||||
"scaling_factor": 0.13025,
|
||||
"up_block_types": [
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:a3ec36b6f3f74d0cb2b005b7c0a1e5426c5ef1e7163b33e463ea57fa049c5996
|
||||
size 849965
|
||||
@@ -70,7 +70,6 @@ def run_lora_sd1_5():
|
||||
|
||||
def run_lora_sdxl():
|
||||
hook_kohya_ss_utils.hook_kohya_ss()
|
||||
import hook_kohya_ss_utils
|
||||
import sdxl_train_network
|
||||
sdxl_train_network.SdxlNetworkTrainer.sample_images = sample_images
|
||||
trainer = sdxl_train_network.SdxlNetworkTrainer()
|
||||
|
||||
@@ -116,12 +116,16 @@ huggingface_hub.file_download._hf_hub_download_to_cache_dir = _hf_hub_download_t
|
||||
import diffusers.loaders.single_file
|
||||
original_snapshot_download = diffusers.loaders.single_file.snapshot_download
|
||||
|
||||
|
||||
def _snapshot_download(repo_id, *args, **kwargs):
|
||||
print(f"_snapshot_download: {repo_id}")
|
||||
if repo_id == "stabilityai/stable-diffusion-3-medium-diffusers":
|
||||
return os.path.join(
|
||||
os.path.dirname(__file__), "configs", "models_config", "stable-diffusion-3-medium-diffusers",)
|
||||
return original_snapshot_download(*args, **kwargs)
|
||||
if repo_id == "runwayml/stable-diffusion-v1-5":
|
||||
return os.path.join(
|
||||
os.path.dirname(__file__), "configs", "models_config", "stable-diffusion-v1-5",)
|
||||
# return original_snapshot_download(repo_id, *args, **kwargs)
|
||||
raise NotImplementedError("_snapshot_download is not supported")
|
||||
|
||||
|
||||
diffusers.loaders.single_file.snapshot_download = _snapshot_download
|
||||
|
||||
+52
-16
@@ -7,6 +7,7 @@ import shutil
|
||||
import sys
|
||||
import json
|
||||
import subprocess
|
||||
import time
|
||||
|
||||
import torch
|
||||
|
||||
@@ -27,17 +28,22 @@ def MZ_KohyaSSInitWorkspace_call(args={}):
|
||||
|
||||
# 切换远程分支 git remote set-branches origin 'main'
|
||||
branch = args.get("branch", "main")
|
||||
subprocess.run(
|
||||
["git", "remote", "set-branches", "origin", branch], cwd=kohya_ss_lora_dir, check=True)
|
||||
subprocess.run(
|
||||
["git", "fetch", "--depth", "1", "origin", branch], cwd=kohya_ss_lora_dir, check=True)
|
||||
|
||||
# 恢复所有文件
|
||||
subprocess.run(
|
||||
["git", "checkout", "."], cwd=kohya_ss_lora_dir, check=True)
|
||||
|
||||
subprocess.run(
|
||||
["git", "checkout", branch], cwd=kohya_ss_lora_dir, check=True)
|
||||
# 查看本地分支是否一致
|
||||
result = subprocess.run(
|
||||
["git", "branch"], cwd=kohya_ss_lora_dir, stdout=subprocess.PIPE, check=True)
|
||||
if branch.encode() not in result.stdout:
|
||||
subprocess.run(
|
||||
["git", "remote", "set-branches", "origin", branch], cwd=kohya_ss_lora_dir, check=True)
|
||||
subprocess.run(
|
||||
["git", "fetch", "--depth", "1", "origin", branch], cwd=kohya_ss_lora_dir, check=True)
|
||||
|
||||
# 恢复所有文件
|
||||
subprocess.run(
|
||||
["git", "checkout", "."], cwd=kohya_ss_lora_dir, check=True)
|
||||
|
||||
subprocess.run(
|
||||
["git", "checkout", branch], cwd=kohya_ss_lora_dir, check=True)
|
||||
|
||||
except Exception as e:
|
||||
raise Exception(f"克隆kohya-ss/sd-scripts或者切换分支时出现异常,详细信息请查看控制台...")
|
||||
@@ -113,9 +119,9 @@ def MZ_KohyaSSUseConfig_call(args={}):
|
||||
raise Exception(f"工作区不存在: {workspace_dir}")
|
||||
|
||||
workspace_config_file = os.path.join(workspace_dir, "config.json")
|
||||
train_config_template = args.get("train_config_template", None)
|
||||
if not os.path.exists(workspace_config_file):
|
||||
train_config_template_dir = args.get("train_config_template_dir", None)
|
||||
train_config_template = args.get("train_config_template", None)
|
||||
|
||||
train_config_template_file = os.path.join(
|
||||
train_config_template_dir, train_config_template + ".json")
|
||||
@@ -125,10 +131,11 @@ def MZ_KohyaSSUseConfig_call(args={}):
|
||||
config = None
|
||||
with open(workspace_config_file, "r", encoding="utf-8") as f:
|
||||
config = json.load(f)
|
||||
|
||||
config["metadata"]["train_type"] = train_config_template
|
||||
ckpt_name = args.get("ckpt_name", "")
|
||||
if ckpt_name == "":
|
||||
raise Exception("未选择模型文件(ckpt_name is required)")
|
||||
|
||||
ckpt_path = folder_paths.get_full_path("checkpoints", ckpt_name)
|
||||
|
||||
config["train_config"]["pretrained_model_name_or_path"] = ckpt_path
|
||||
@@ -137,13 +144,43 @@ def MZ_KohyaSSUseConfig_call(args={}):
|
||||
output_dir = os.path.join(workspace_dir, "output")
|
||||
config["train_config"]["output_dir"] = output_dir
|
||||
|
||||
datetime = time.strftime("%Y%m%d_%H%M%S", time.localtime())
|
||||
# output_name
|
||||
config["train_config"]["output_name"] = workspace_name
|
||||
config["train_config"]["output_name"] = f"{workspace_name}_{train_config_template}_{datetime}"
|
||||
|
||||
dataset_config_path = os.path.join(
|
||||
workspace_dir, "dataset.toml")
|
||||
config["train_config"]["dataset_config"] = dataset_config_path
|
||||
|
||||
config["train_config"]["max_train_steps"] = str(
|
||||
args.get("max_train_steps"))
|
||||
|
||||
config["train_config"]["max_train_epochs"] = str(
|
||||
args.get("max_train_epochs"))
|
||||
|
||||
config["train_config"]["save_every_n_epochs"] = str(
|
||||
args.get("save_every_n_epochs"))
|
||||
|
||||
config["train_config"]["learning_rate"] = str(
|
||||
args.get("learning_rate"))
|
||||
|
||||
advanced_config = args.get("advanced_config", {}).copy()
|
||||
|
||||
for k in advanced_config:
|
||||
if type(advanced_config[k]) == str and advanced_config[k] == "":
|
||||
if k in config["train_config"]:
|
||||
del config["train_config"][k]
|
||||
continue
|
||||
elif advanced_config[k] == "enable":
|
||||
advanced_config[k] = True
|
||||
elif advanced_config[k] == "disable":
|
||||
advanced_config[k] = False
|
||||
else:
|
||||
advanced_config[k] = str(advanced_config[k])
|
||||
config["train_config"][k] = advanced_config[k]
|
||||
|
||||
# raise Exception(f"args: {json.dumps(config, indent=4)}")
|
||||
|
||||
if config is None:
|
||||
raise Exception(f"读取配置文件失败: {workspace_config_file}")
|
||||
|
||||
@@ -160,6 +197,8 @@ def config2args(train_parser: argparse.ArgumentParser, config):
|
||||
try:
|
||||
config_args_list = []
|
||||
for key, value in config.items():
|
||||
if value is None:
|
||||
continue
|
||||
if type(value) == bool:
|
||||
if value:
|
||||
config_args_list.append(f"--{key}")
|
||||
@@ -329,9 +368,6 @@ def MZ_KohyaSSTrain_call(args={}):
|
||||
elif train_type == "lora_sdxl":
|
||||
run_hook_kohya_ss_run_file(kohya_ss_tool_dir, config.get(
|
||||
"train_config"), "run_lora_sdxl")
|
||||
elif train_type == "lora_sd3":
|
||||
run_hook_kohya_ss_run_file(kohya_ss_tool_dir, config.get(
|
||||
"train_config"), "run_lora_sd3")
|
||||
else:
|
||||
raise Exception(
|
||||
f"暂时不支持的训练类型: {train_type}")
|
||||
|
||||
Reference in New Issue
Block a user