add partcrafter
This commit is contained in:
 Denis Kochetov
@@ -0,0 +1,35 @@
|
||||
*.7z filter=lfs diff=lfs merge=lfs -text
|
||||
*.arrow filter=lfs diff=lfs merge=lfs -text
|
||||
*.bin filter=lfs diff=lfs merge=lfs -text
|
||||
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
||||
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
||||
*.ftz filter=lfs diff=lfs merge=lfs -text
|
||||
*.gz filter=lfs diff=lfs merge=lfs -text
|
||||
*.h5 filter=lfs diff=lfs merge=lfs -text
|
||||
*.joblib filter=lfs diff=lfs merge=lfs -text
|
||||
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
||||
*.model filter=lfs diff=lfs merge=lfs -text
|
||||
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
||||
*.npy filter=lfs diff=lfs merge=lfs -text
|
||||
*.npz filter=lfs diff=lfs merge=lfs -text
|
||||
*.onnx filter=lfs diff=lfs merge=lfs -text
|
||||
*.ot filter=lfs diff=lfs merge=lfs -text
|
||||
*.parquet filter=lfs diff=lfs merge=lfs -text
|
||||
*.pb filter=lfs diff=lfs merge=lfs -text
|
||||
*.pickle filter=lfs diff=lfs merge=lfs -text
|
||||
*.pkl filter=lfs diff=lfs merge=lfs -text
|
||||
*.pt filter=lfs diff=lfs merge=lfs -text
|
||||
*.pth filter=lfs diff=lfs merge=lfs -text
|
||||
*.rar filter=lfs diff=lfs merge=lfs -text
|
||||
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
||||
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
||||
*.tar filter=lfs diff=lfs merge=lfs -text
|
||||
*.tflite filter=lfs diff=lfs merge=lfs -text
|
||||
*.tgz filter=lfs diff=lfs merge=lfs -text
|
||||
*.wasm filter=lfs diff=lfs merge=lfs -text
|
||||
*.xz filter=lfs diff=lfs merge=lfs -text
|
||||
*.zip filter=lfs diff=lfs merge=lfs -text
|
||||
*.zst filter=lfs diff=lfs merge=lfs -text
|
||||
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
||||
@@ -0,0 +1,18 @@
|
||||
---
|
||||
license: mit
|
||||
pipeline_tag: image-to-3d
|
||||
tags:
|
||||
- partcrafter
|
||||
- 3d-generation
|
||||
- rectified-flow
|
||||
---
|
||||
# PartCrafter: Structured 3D Mesh Generation via Compositional Latent Diffusion Transformers
|
||||
|
||||
PartCrafter is a structured 3D generative model that jointly generates multiple parts and objects from a single RGB image in one shot.
|
||||
This HuggingFace🤗 repo stores pretrained model weights for PartCrafter on **object level**.
|
||||
|
||||
For more details about usage, please refer to the [official GitHub repo](https://github.com/wgsxm/PartCrafter).
|
||||
|
||||
- Project page: https://wgsxm.github.io/projects/partcrafter/
|
||||
- Code: https://github.com/wgsxm/PartCrafter
|
||||
- Paper: https://arxiv.org/abs/2506.05573
|
||||
+27
@@ -0,0 +1,27 @@
|
||||
{
|
||||
"crop_size": {
|
||||
"height": 224,
|
||||
"width": 224
|
||||
},
|
||||
"do_center_crop": true,
|
||||
"do_convert_rgb": true,
|
||||
"do_normalize": true,
|
||||
"do_rescale": true,
|
||||
"do_resize": true,
|
||||
"image_mean": [
|
||||
0.485,
|
||||
0.456,
|
||||
0.406
|
||||
],
|
||||
"image_processor_type": "BitImageProcessor",
|
||||
"image_std": [
|
||||
0.229,
|
||||
0.224,
|
||||
0.225
|
||||
],
|
||||
"resample": 3,
|
||||
"rescale_factor": 0.00392156862745098,
|
||||
"size": {
|
||||
"shortest_edge": 256
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,60 @@
|
||||
{
|
||||
"apply_layernorm": true,
|
||||
"architectures": [
|
||||
"Dinov2Model"
|
||||
],
|
||||
"attention_probs_dropout_prob": 0.0,
|
||||
"drop_path_rate": 0.0,
|
||||
"hidden_act": "gelu",
|
||||
"hidden_dropout_prob": 0.0,
|
||||
"hidden_size": 1024,
|
||||
"image_size": 518,
|
||||
"initializer_range": 0.02,
|
||||
"layer_norm_eps": 1e-06,
|
||||
"layerscale_value": 1.0,
|
||||
"mlp_ratio": 4,
|
||||
"model_type": "dinov2",
|
||||
"num_attention_heads": 16,
|
||||
"num_channels": 3,
|
||||
"num_hidden_layers": 24,
|
||||
"out_features": [
|
||||
"stage24"
|
||||
],
|
||||
"out_indices": [
|
||||
24
|
||||
],
|
||||
"patch_size": 14,
|
||||
"qkv_bias": true,
|
||||
"reshape_hidden_states": true,
|
||||
"stage_names": [
|
||||
"stem",
|
||||
"stage1",
|
||||
"stage2",
|
||||
"stage3",
|
||||
"stage4",
|
||||
"stage5",
|
||||
"stage6",
|
||||
"stage7",
|
||||
"stage8",
|
||||
"stage9",
|
||||
"stage10",
|
||||
"stage11",
|
||||
"stage12",
|
||||
"stage13",
|
||||
"stage14",
|
||||
"stage15",
|
||||
"stage16",
|
||||
"stage17",
|
||||
"stage18",
|
||||
"stage19",
|
||||
"stage20",
|
||||
"stage21",
|
||||
"stage22",
|
||||
"stage23",
|
||||
"stage24"
|
||||
],
|
||||
"torch_dtype": "float16",
|
||||
"transformers_version": "4.53.0",
|
||||
"use_mask_token": true,
|
||||
"use_swiglu_ffn": false
|
||||
}
|
||||
@@ -0,0 +1,24 @@
|
||||
{
|
||||
"_class_name": "PartCrafterPipeline",
|
||||
"_diffusers_version": "0.34.0",
|
||||
"feature_extractor_dinov2": [
|
||||
"transformers",
|
||||
"BitImageProcessor"
|
||||
],
|
||||
"image_encoder_dinov2": [
|
||||
"transformers",
|
||||
"Dinov2Model"
|
||||
],
|
||||
"scheduler": [
|
||||
"partcrafter_src.schedulers.scheduling_rectified_flow",
|
||||
"RectifiedFlowScheduler"
|
||||
],
|
||||
"transformer": [
|
||||
"partcrafter_src.models.transformers.partcrafter_transformer",
|
||||
"PartCrafterDiTModel"
|
||||
],
|
||||
"vae": [
|
||||
"partcrafter_src.models.autoencoders.autoencoder_kl_triposg",
|
||||
"TripoSGVAEModel"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,7 @@
|
||||
{
|
||||
"_class_name": "RectifiedFlowScheduler",
|
||||
"_diffusers_version": "0.34.0",
|
||||
"num_train_timesteps": 1000,
|
||||
"shift": 1,
|
||||
"use_dynamic_shifting": false
|
||||
}
|
||||
@@ -0,0 +1,27 @@
|
||||
{
|
||||
"_class_name": "PartCrafterDiTModel",
|
||||
"_diffusers_version": "0.34.0",
|
||||
"cross_attention_dim": 1024,
|
||||
"enable_global_cross_attn": true,
|
||||
"enable_local_cross_attn": true,
|
||||
"enable_part_embedding": true,
|
||||
"global_attn_block_id_range": null,
|
||||
"global_attn_block_ids": [
|
||||
0,
|
||||
2,
|
||||
4,
|
||||
6,
|
||||
8,
|
||||
10,
|
||||
12,
|
||||
14,
|
||||
16,
|
||||
18,
|
||||
20
|
||||
],
|
||||
"in_channels": 64,
|
||||
"max_num_parts": 32,
|
||||
"num_attention_heads": 16,
|
||||
"num_layers": 21,
|
||||
"width": 2048
|
||||
}
|
||||
@@ -0,0 +1,15 @@
|
||||
{
|
||||
"_class_name": "TripoSGVAEModel",
|
||||
"_diffusers_version": "0.34.0",
|
||||
"_name_or_path": "pretrained_weights/TripoSG",
|
||||
"embed_frequency": 8,
|
||||
"embed_include_pi": false,
|
||||
"embedding_type": "frequency",
|
||||
"in_channels": 3,
|
||||
"latent_channels": 64,
|
||||
"num_attention_heads": 8,
|
||||
"num_layers_decoder": 16,
|
||||
"num_layers_encoder": 8,
|
||||
"width_decoder": 1024,
|
||||
"width_encoder": 512
|
||||
}
|
||||
@@ -0,0 +1,7 @@
|
||||
__pycache__
|
||||
wandb
|
||||
output
|
||||
preprocessed_data
|
||||
pretrained_weights
|
||||
results
|
||||
output_partcrafter
|
||||
@@ -0,0 +1,21 @@
|
||||
MIT License
|
||||
|
||||
Copyright (c) 2025 Yuchen Lin
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
of this software and associated documentation files (the "Software"), to deal
|
||||
in the Software without restriction, including without limitation the rights
|
||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
copies of the Software, and to permit persons to whom the Software is
|
||||
furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all
|
||||
copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
SOFTWARE.
|
||||
@@ -0,0 +1,143 @@
|
||||
# PartCrafter: Structured 3D Mesh Generation via Compositional Latent Diffusion Transformers
|
||||
|
||||
<h4 align="center">
|
||||
|
||||
[Yuchen Lin<sup>*</sup>](https://wgsxm.github.io), [Chenguo Lin<sup>*</sup>](https://chenguolin.github.io), [Panwang Pan<sup>†</sup>](https://paulpanwang.github.io), [Honglei Yan](https://openreview.net/profile?id=~Honglei_Yan1), [Yiqiang Feng](https://openreview.net/profile?id=~Feng_Yiqiang1), [Yadong Mu](http://www.muyadong.com), [Katerina Fragkiadaki](https://www.cs.cmu.edu/~katef/)
|
||||
|
||||
[](https://arxiv.org/abs/2506.05573)
|
||||
[](https://wgsxm.github.io/projects/partcrafter)
|
||||
[<img src="https://img.shields.io/badge/YouTube-Video-red" alt="YouTube">](https://www.youtube.com/watch?v=ZaZHbkkPtXY)
|
||||
[](https://huggingface.co/wgsxm/PartCrafter)
|
||||
[](./LICENSE)
|
||||
|
||||
<p align="center">
|
||||
<img width="90%" alt="pipeline", src="./assets/teaser.png">
|
||||
</p>
|
||||
|
||||
</h4>
|
||||
|
||||
This repository contains the official implementation of the paper: [PartCrafter: Structured 3D Mesh Generation via Compositional Latent Diffusion Transformers](https://wgsxm.github.io/projects/partcrafter/).
|
||||
PartCrafter is a structured 3D generative model that jointly generates multiple parts and objects from a single RGB image in one shot.
|
||||
Here is our [Project Page](https://wgsxm.github.io/projects/partcrafter).
|
||||
|
||||
Feel free to contact me (linyuchen@stu.pku.edu.cn) or open an issue if you have any questions or suggestions.
|
||||
|
||||
|
||||
## 📢 News
|
||||
- **2025-07-20**: A guide for installing PartCrafter on Windows is available in [this fork](https://github.com/JackDainzh/PartCrafter-Windows/tree/windows-main). Thanks to [JackDainzh](https://github.com/JackDainzh)!
|
||||
- **2025-07-13**: PartCrafter is fully open-sourced 🚀.
|
||||
- **2025-06-09**: PartCrafter is on arXiv.
|
||||
|
||||
## 📋 TODO
|
||||
- [x] Release inference scripts and pretrained checkpoints.
|
||||
- [x] Release training code and data preprocessing scripts.
|
||||
- [ ] Provide a HuggingFace🤗 demo.
|
||||
- [ ] Release preprocessed dataset.
|
||||
|
||||
## 🔧 Installation
|
||||
We use `torch-2.5.1+cu124` and `python-3.11`. But it should also work with other versions. Create a conda environment with the following command (optional):
|
||||
```
|
||||
conda create -n partcrafter python=3.11.13
|
||||
conda activate partcrafter
|
||||
pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 --index-url https://download.pytorch.org/whl/cu124
|
||||
```
|
||||
Then, install other dependencies with the following command:
|
||||
```
|
||||
git clone https://github.com/wgsxm/PartCrafter.git
|
||||
cd PartCrafter
|
||||
bash settings/setup.sh
|
||||
```
|
||||
If you do not have root access and use conda environment, you can install required graphics libraries with the following command:
|
||||
```
|
||||
conda install -c conda-forge libegl libglu pyopengl
|
||||
```
|
||||
We test the above installation on Debian 12 with NVIDIA H20 GPUs. For Windows users, you can try to set up the environment according to [this pull request](https://github.com/wgsxm/PartCrafter/pull/24) and [this fork](https://github.com/JackDainzh/PartCrafter-Windows/tree/windows-main). We sincerely thank [JackDainzh](https://github.com/JackDainzh) for contributing to the Windows support!
|
||||
|
||||
## 💡 Quick Start
|
||||
<p align="center">
|
||||
<img width="90%" alt="pipeline", src="./assets/robot.gif">
|
||||
</p>
|
||||
|
||||
Generate a 3D part-level object from an image:
|
||||
```
|
||||
python scripts/inference_partcrafter.py \
|
||||
--image_path assets/images/np3_2f6ab901c5a84ed6bbdf85a67b22a2ee.png \
|
||||
--num_parts 3 --tag robot --render
|
||||
```
|
||||
The required model weights will be automatically downloaded:
|
||||
- PartCrafter model from [wgsxm/PartCrafter](https://huggingface.co/wgsxm/PartCrafter) → pretrained_weights/PartCrafter
|
||||
- RMBG model from [briaai/RMBG-1.4](http://huggingface.co/briaai/RMBG-1.4) → pretrained_weights/RMBG-1.4
|
||||
|
||||
The generated results will be saved to `./results/robot`. We provide several example images from Objaverse and ABO in `./assets/images`. Their filenames start with recommended number of parts, e.g., `np3` which means 3 parts. You can also try other part count for the same input images.
|
||||
|
||||
Specify `--rmbg` if you use custom images. **This will remove the background of the input image and resize it appropriately.**
|
||||
|
||||
## 💻 System Requirements
|
||||
A CUDA-enabled GPU with at least 8GB VRAM. You can reduce number of parts or number of tokens to save GPU memory. We set the number of tokens per part to `1024` by default for better quality.
|
||||
|
||||
## 📊 Dataset
|
||||
Please refer to [Dataset README](./datasets/README.md) to download and preprocess the dataset. To generate a minimal dataset, you can run:
|
||||
```
|
||||
python datasets/preprocess/preprocess.py --input assets/objects --output preprocessed_data
|
||||
```
|
||||
This script preprocesses GLB files in `./assets/objects` and saves the preprocessed data to `./preprocessed_data`. We provide a pseudo data configuration [here](./datasets/object_part_configs.json), which makes use of the minimal preprocessed data and is compatible with the training settings.
|
||||
|
||||
## 🦾 Training
|
||||
To train PartCrafter from scratch, you first need to download TripoSG from [VAST-AI/TripoSG](https://huggingface.co/VAST-AI/TripoSG) and store the weights in `./pretrained_models/TripoSG`.
|
||||
```
|
||||
huggingface-cli download VAST-AI/TripoSG --local-dir pretrained_weights/TripoSG
|
||||
```
|
||||
|
||||
Our training scripts are suitable for training with 8 H20 GPUs (96G VRAM each). Currently, we only finetune the DiT of TripoSG and keep the VAE fixed. But you can also finetune the VAE of TripoSG, which should improve the quality of the generated 3D parts. PartCrafter is compatible with all 3D object generative models based on vector sets such as [Hunyuan3D-2.1](https://github.com/Tencent-Hunyuan/Hunyuan3D-2.1). We warmly welcome pull requests from the community.
|
||||
|
||||
We provide several training configurations [here](./configs). You should modify the path of dataset configs in the training config files, which is currently set to `./datasets/object_part_configs.json`.
|
||||
|
||||
If you use `wandb`, you should also modify the `WANDB_API_KEY` in the training script. If you have trouble connecting to `wandb`, try `export WANDB_BASE_URL=https://api.bandw.top`.
|
||||
|
||||
Train PartCrafter from TripoSG:
|
||||
```
|
||||
bash scripts/train_partcrafter.sh --config configs/mp8_nt512.yaml --use_ema \
|
||||
--gradient_accumulation_steps 4 \
|
||||
--output_dir output_partcrafter \
|
||||
--tag scaleup_mp8_nt512
|
||||
```
|
||||
|
||||
Finetune PartCrafter with larger number of parts:
|
||||
```
|
||||
bash scripts/train_partcrafter.sh --config configs/mp16_nt512.yaml --use_ema \
|
||||
--gradient_accumulation_steps 4 \
|
||||
--output_dir output_partcrafter \
|
||||
--load_pretrained_model scaleup_mp8_nt512 \
|
||||
--load_pretrained_model_ckpt 10 \
|
||||
--tag scaleup_mp16_nt512
|
||||
```
|
||||
|
||||
Finetune PartCrafter with more tokens:
|
||||
```
|
||||
bash scripts/train_partcrafter.sh --config configs/mp16_nt1024.yaml --use_ema \
|
||||
--gradient_accumulation_steps 4 \
|
||||
--output_dir output_partcrafter \
|
||||
--load_pretrained_model scaleup_mp16_nt512 \
|
||||
--load_pretrained_model_ckpt 10 \
|
||||
--tag scaleup_mp16_nt1024
|
||||
```
|
||||
|
||||
## 😊 Acknowledgement
|
||||
We would like to thank the authors of [DiffSplat](https://chenguolin.github.io/projects/DiffSplat/), [TripoSG](https://yg256li.github.io/TripoSG-Page/), [HoloPart](https://vast-ai-research.github.io/HoloPart/), and [MIDI-3D](https://huanngzh.github.io/MIDI-Page/)
|
||||
for their great work and generously providing source codes, which inspired our work and helped us a lot in the implementation.
|
||||
|
||||
|
||||
## 📚 Citation
|
||||
If you find our work helpful, please consider citing:
|
||||
```bibtex
|
||||
@misc{lin2025partcrafter,
|
||||
title={PartCrafter: Structured 3D Mesh Generation via Compositional Latent Diffusion Transformers},
|
||||
author={Yuchen Lin and Chenguo Lin and Panwang Pan and Honglei Yan and Yiqiang Feng and Yadong Mu and Katerina Fragkiadaki},
|
||||
year={2025},
|
||||
eprint={2506.05573},
|
||||
url={https://arxiv.org/abs/2506.05573}
|
||||
}
|
||||
```
|
||||
|
||||
## 🌟 Star History
|
||||
[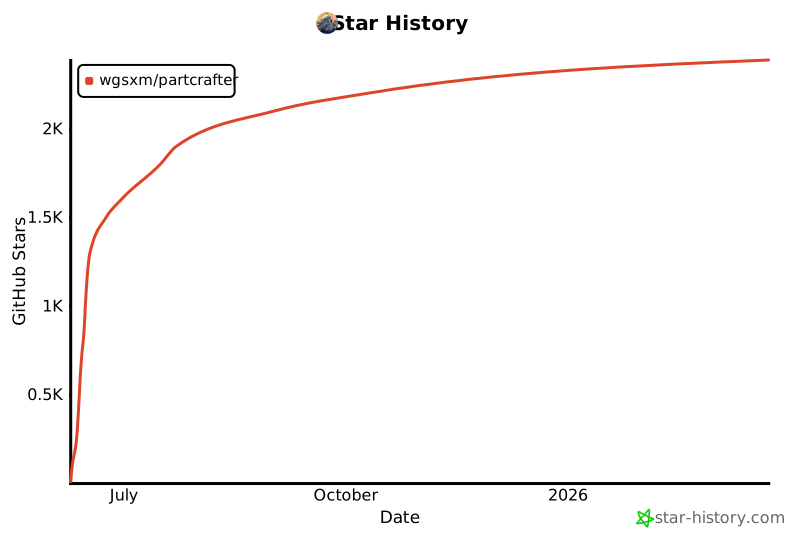](https://www.star-history.com/#wgsxm/PartCrafter&Date)
|
||||
@@ -0,0 +1,7 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
# Add current directory to sys.path so partcrafter_src modules can be imported
|
||||
current_dir = os.path.dirname(os.path.abspath(__file__))
|
||||
if current_dir not in sys.path:
|
||||
sys.path.append(current_dir)
|
||||
@@ -0,0 +1,77 @@
|
||||
model:
|
||||
pretrained_model_name_or_path: 'pretrained_weights/TripoSG'
|
||||
vae:
|
||||
num_tokens: 1024
|
||||
transformer:
|
||||
enable_local_cross_attn: true
|
||||
global_attn_block_ids: [0, 2, 4, 6, 8, 10, 12, 14, 16, 18, 20]
|
||||
global_attn_block_id_range: null # The average should be 10 for unet-skipping
|
||||
|
||||
|
||||
dataset:
|
||||
config:
|
||||
- 'datasets/object_part_configs.json' # Modify this path if you use your own dataset
|
||||
training_ratio: 0.9
|
||||
min_num_parts: 1
|
||||
max_num_parts: 16
|
||||
max_iou_mean: 0.2
|
||||
max_iou_max: 0.2
|
||||
shuffle_parts: true
|
||||
object_ratio: 0.3
|
||||
rotating_ratio: 0.2
|
||||
ratating_degree: 10
|
||||
|
||||
optimizer:
|
||||
name: "adamw"
|
||||
lr: 5e-5
|
||||
betas:
|
||||
- 0.9
|
||||
- 0.999
|
||||
weight_decay: 0.01
|
||||
eps: 1.e-8
|
||||
|
||||
lr_scheduler:
|
||||
name: "constant_warmup"
|
||||
num_warmup_steps: 1000
|
||||
|
||||
train:
|
||||
batch_size_per_gpu: 32
|
||||
epochs: 10
|
||||
grad_checkpoint: true
|
||||
weighting_scheme: "logit_normal"
|
||||
logit_mean: 0.0
|
||||
logit_std: 1.0
|
||||
mode_scale: 1.29
|
||||
cfg_dropout_prob: 0.1
|
||||
training_objective: "-v"
|
||||
log_freq: 1
|
||||
early_eval_freq: 500
|
||||
early_eval: 1000
|
||||
eval_freq: 1000
|
||||
save_freq: 2000
|
||||
eval_freq_epoch: 5
|
||||
save_freq_epoch: 10
|
||||
ema_kwargs:
|
||||
decay: 0.9999
|
||||
use_ema_warmup: true
|
||||
inv_gamma: 1.
|
||||
power: 0.75
|
||||
|
||||
val:
|
||||
batch_size_per_gpu: 1
|
||||
nrow: 4
|
||||
min_num_parts: 2
|
||||
max_num_parts: 8
|
||||
num_inference_steps: 50
|
||||
max_num_expanded_coords: 1e8
|
||||
use_flash_decoder: false
|
||||
rendering:
|
||||
radius: 4.0
|
||||
num_views: 36
|
||||
fps: 18
|
||||
metric:
|
||||
cd_num_samples: 204800
|
||||
cd_metric: "l2"
|
||||
f1_score_threshold: 0.1
|
||||
default_cd: 1e6
|
||||
default_f1: 0.0
|
||||
@@ -0,0 +1,77 @@
|
||||
model:
|
||||
pretrained_model_name_or_path: 'pretrained_weights/TripoSG'
|
||||
vae:
|
||||
num_tokens: 512
|
||||
transformer:
|
||||
enable_local_cross_attn: true
|
||||
global_attn_block_ids: [0, 2, 4, 6, 8, 10, 12, 14, 16, 18, 20]
|
||||
global_attn_block_id_range: null # The average should be 10 for unet-skipping
|
||||
|
||||
|
||||
dataset:
|
||||
config:
|
||||
- 'datasets/object_part_configs.json' # Modify this path if you use your own dataset
|
||||
training_ratio: 0.9
|
||||
min_num_parts: 1
|
||||
max_num_parts: 16
|
||||
max_iou_mean: 0.5
|
||||
max_iou_max: 0.5
|
||||
shuffle_parts: true
|
||||
object_ratio: 0.3
|
||||
rotating_ratio: 0.2
|
||||
ratating_degree: 10
|
||||
|
||||
optimizer:
|
||||
name: "adamw"
|
||||
lr: 5e-5
|
||||
betas:
|
||||
- 0.9
|
||||
- 0.999
|
||||
weight_decay: 0.01
|
||||
eps: 1.e-8
|
||||
|
||||
lr_scheduler:
|
||||
name: "constant_warmup"
|
||||
num_warmup_steps: 1000
|
||||
|
||||
train:
|
||||
batch_size_per_gpu: 32
|
||||
epochs: 10
|
||||
grad_checkpoint: true
|
||||
weighting_scheme: "logit_normal"
|
||||
logit_mean: 0.0
|
||||
logit_std: 1.0
|
||||
mode_scale: 1.29
|
||||
cfg_dropout_prob: 0.1
|
||||
training_objective: "-v"
|
||||
log_freq: 1
|
||||
early_eval_freq: 500
|
||||
early_eval: 1000
|
||||
eval_freq: 1000
|
||||
save_freq: 2000
|
||||
eval_freq_epoch: 5
|
||||
save_freq_epoch: 10
|
||||
ema_kwargs:
|
||||
decay: 0.9999
|
||||
use_ema_warmup: true
|
||||
inv_gamma: 1.
|
||||
power: 0.75
|
||||
|
||||
val:
|
||||
batch_size_per_gpu: 1
|
||||
nrow: 4
|
||||
min_num_parts: 2
|
||||
max_num_parts: 8
|
||||
num_inference_steps: 50
|
||||
max_num_expanded_coords: 1e8
|
||||
use_flash_decoder: false
|
||||
rendering:
|
||||
radius: 4.0
|
||||
num_views: 36
|
||||
fps: 18
|
||||
metric:
|
||||
cd_num_samples: 204800
|
||||
cd_metric: "l2"
|
||||
f1_score_threshold: 0.1
|
||||
default_cd: 1e6
|
||||
default_f1: 0.0
|
||||
@@ -0,0 +1,77 @@
|
||||
model:
|
||||
pretrained_model_name_or_path: 'pretrained_weights/TripoSG'
|
||||
vae:
|
||||
num_tokens: 512
|
||||
transformer:
|
||||
enable_local_cross_attn: true
|
||||
global_attn_block_ids: [0, 2, 4, 6, 8, 10, 12, 14, 16, 18, 20]
|
||||
global_attn_block_id_range: null # The average should be 10 for unet-skipping
|
||||
|
||||
|
||||
dataset:
|
||||
config:
|
||||
- 'datasets/object_part_configs.json' # Modify this path if you use your own dataset
|
||||
training_ratio: 0.9
|
||||
min_num_parts: 1
|
||||
max_num_parts: 8
|
||||
max_iou_mean: 0.5
|
||||
max_iou_max: 0.5
|
||||
shuffle_parts: true
|
||||
object_ratio: 0.3
|
||||
rotating_ratio: 0.2
|
||||
ratating_degree: 10
|
||||
|
||||
optimizer:
|
||||
name: "adamw"
|
||||
lr: 1e-4
|
||||
betas:
|
||||
- 0.9
|
||||
- 0.999
|
||||
weight_decay: 0.01
|
||||
eps: 1.e-8
|
||||
|
||||
lr_scheduler:
|
||||
name: "constant_warmup"
|
||||
num_warmup_steps: 1000
|
||||
|
||||
train:
|
||||
batch_size_per_gpu: 32
|
||||
epochs: 10
|
||||
grad_checkpoint: true
|
||||
weighting_scheme: "logit_normal"
|
||||
logit_mean: 0.0
|
||||
logit_std: 1.0
|
||||
mode_scale: 1.29
|
||||
cfg_dropout_prob: 0.1
|
||||
training_objective: "-v"
|
||||
log_freq: 1
|
||||
early_eval_freq: 500
|
||||
early_eval: 1000
|
||||
eval_freq: 1000
|
||||
save_freq: 2000
|
||||
eval_freq_epoch: 5
|
||||
save_freq_epoch: 10
|
||||
ema_kwargs:
|
||||
decay: 0.9999
|
||||
use_ema_warmup: true
|
||||
inv_gamma: 1.
|
||||
power: 0.75
|
||||
|
||||
val:
|
||||
batch_size_per_gpu: 1
|
||||
nrow: 4
|
||||
min_num_parts: 2
|
||||
max_num_parts: 8
|
||||
num_inference_steps: 50
|
||||
max_num_expanded_coords: 1e8
|
||||
use_flash_decoder: false
|
||||
rendering:
|
||||
radius: 4.0
|
||||
num_views: 36
|
||||
fps: 18
|
||||
metric:
|
||||
cd_num_samples: 204800
|
||||
cd_metric: "l2"
|
||||
f1_score_threshold: 0.1
|
||||
default_cd: 1e6
|
||||
default_f1: 0.0
|
||||
@@ -0,0 +1,64 @@
|
||||
# Dataset Preparation
|
||||
We provide the data preprocessing pipeline for PartCrafter. By following the instructions, you can generate the training data from the raw GLB data. While we are considering releasing the preprocessed dataset, please note that it may take some time before it becomes available.
|
||||
|
||||
## Download Raw Data
|
||||
Our final model uses a subset of [Objaverse](https://huggingface.co/datasets/allenai/objaverse) provided by [LGM](https://github.com/ashawkey/objaverse_filter) and [Amazon Berkeley Objects (ABO) Dataset](https://amazon-berkeley-objects.s3.amazonaws.com/index.html). Please download the raw GLB files according to their instructions. You can also use other source of data.
|
||||
|
||||
## Data Preprocess
|
||||
We provide several scripts to preprocess the raw GLB files [here](./preprocess/). These scripts are minimal implementations and illustrate the whole preprocessing pipeline on a single 3D object.
|
||||
|
||||
1. Sample points from mesh surface
|
||||
```
|
||||
python datasets/preprocess/mesh_to_point.py --input assets/objects/scissors.glb --output preprocessed_data
|
||||
```
|
||||
|
||||
2. Render images
|
||||
```
|
||||
python datasets/preprocess/render.py --input assets/objects/scissors.glb --output preprocessed_data
|
||||
```
|
||||
|
||||
3. Remove background for rendered images and resize to 90%
|
||||
```
|
||||
python datasets/preprocess/rmbg.py --input preprocessed_data/scissors/rendering.png --output preprocessed_data
|
||||
```
|
||||
|
||||
4. (Optional) Calculate IoU
|
||||
```
|
||||
python datasets/preprocess/calculate_iou.py --input assets/objects/scissors.glb --output preprocessed_data
|
||||
```
|
||||
After preprocessing, you can generate a dataset configuration file according to the example configuration file with your own data path.
|
||||
|
||||
To preprocess a folder of meshes, run
|
||||
```
|
||||
python datasets/preprocess/preprocess.py --input assets/objects --output preprocessed_data
|
||||
```
|
||||
This will also generate a configuration file in `./preprocessed_data/object_part_configs.json`.
|
||||
|
||||
## Dataset Configuration
|
||||
The training code requires specific format of dataset configuration. I provide an example configuration [here](example_configs.json). You can use it as a template to configure your own dataset. A minimal legal configuration file should be like:
|
||||
|
||||
```
|
||||
[
|
||||
{
|
||||
"mesh_path": "/path/to/object.glb",
|
||||
"surface_path": "/path/to/object.npy",
|
||||
"image_path": "/path/to/object.png",
|
||||
"num_parts": 4,
|
||||
"iou_mean": 0.5,
|
||||
"iou_max": 0.9,
|
||||
"valid": true
|
||||
},
|
||||
{
|
||||
...
|
||||
},
|
||||
...
|
||||
]
|
||||
```
|
||||
Explaination:
|
||||
- `mesh_path`: The path to the GLB file of the object.
|
||||
- `surface_path`: The path to the npy file of the object surface points.
|
||||
- `image_path`: The path to the rendered image of the object (after removing background).
|
||||
- `num_parts`: The number of parts of the object.
|
||||
- `iou_mean`: The mean IoU of the object parts.
|
||||
- `iou_max`: The max IoU of the object parts.
|
||||
- `valid`: Whether the object is valid. If set to false, the object will be filtered out during training.
|
||||
@@ -0,0 +1,38 @@
|
||||
[
|
||||
{
|
||||
"dataset": "objaverse",
|
||||
"file": "0007a7c8fcb44074b20fa4e14b8730a6.glb",
|
||||
"folder": "000",
|
||||
"num_parts": 1,
|
||||
"valid": true,
|
||||
"mesh_path": "/datasets/objaverse/000/0007a7c8fcb44074b20fa4e14b8730a6.glb",
|
||||
"surface_path": "/datasets/objaverse_point/000/0007a7c8fcb44074b20fa4e14b8730a6.npy",
|
||||
"image_path": "/datasets/objaverse_rendering_rmbg/000/0007a7c8fcb44074b20fa4e14b8730a6.png",
|
||||
"iou_mean": 0.0,
|
||||
"iou_max": 0.0
|
||||
},
|
||||
{
|
||||
"dataset": "objaverse",
|
||||
"file": "e05d63a78f2c44c5a64fbc419998e603.glb",
|
||||
"folder": "001",
|
||||
"num_parts": 7,
|
||||
"valid": true,
|
||||
"mesh_path": "/datasets/objaverse/001/e05d63a78f2c44c5a64fbc419998e603.glb",
|
||||
"surface_path": "/datasets/objaverse_point/001/e05d63a78f2c44c5a64fbc419998e603.npy",
|
||||
"image_path": "/datasets/objaverse_rendering_rmbg/001/e05d63a78f2c44c5a64fbc419998e603.png",
|
||||
"iou_mean": 0.0005096137625985897,
|
||||
"iou_max": 0.0022603978300180833
|
||||
},
|
||||
{
|
||||
"dataset": "objaverse",
|
||||
"file": "e0a9d033f27043339eb724ec5b7f5fdc.glb",
|
||||
"folder": "002",
|
||||
"num_parts": 3,
|
||||
"valid": true,
|
||||
"mesh_path": "/datasets/objaverse/002/e0a9d033f27043339eb724ec5b7f5fdc.glb",
|
||||
"surface_path": "/datasets/objaverse_point/002/e0a9d033f27043339eb724ec5b7f5fdc.npy",
|
||||
"image_path": "/datasets/objaverse_rendering_rmbg/002/e0a9d033f27043339eb724ec5b7f5fdc.png",
|
||||
"iou_mean": 0.0683491062039958,
|
||||
"iou_max": 0.20504731861198738
|
||||
}
|
||||
]
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,42 @@
|
||||
import os
|
||||
import trimesh
|
||||
import numpy as np
|
||||
import argparse
|
||||
import json
|
||||
|
||||
from partcrafter_src.utils.data_utils import normalize_mesh
|
||||
from partcrafter_src.utils.metric_utils import compute_IoU_for_scene
|
||||
|
||||
if __name__ == '__main__':
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument('--input', type=str, default='assets/objects/scissors.glb')
|
||||
parser.add_argument('--output', type=str, default='preprocessed_data')
|
||||
args = parser.parse_args()
|
||||
|
||||
input_path = args.input
|
||||
output_path = args.output
|
||||
|
||||
assert os.path.exists(input_path), f'{input_path} does not exist'
|
||||
|
||||
mesh_name = os.path.basename(input_path).split('.')[0]
|
||||
output_path = os.path.join(output_path, mesh_name)
|
||||
if not os.path.exists(output_path):
|
||||
os.makedirs(output_path)
|
||||
|
||||
config = {
|
||||
'iou_mean': 0.0,
|
||||
'iou_max': 0.0,
|
||||
'iou_list': [],
|
||||
}
|
||||
mesh = normalize_mesh(trimesh.load(input_path, process=False))
|
||||
try:
|
||||
iou_list = compute_IoU_for_scene(mesh, return_type='iou_list')
|
||||
config['iou_list'] = iou_list
|
||||
config['iou_mean'] = np.mean(iou_list)
|
||||
config['iou_max'] = np.max(iou_list)
|
||||
except:
|
||||
config['iou_list'] = []
|
||||
config['iou_mean'] = 0.0
|
||||
config['iou_max'] = 0.0
|
||||
|
||||
json.dump(config, open(os.path.join(output_path, f'iou.json'), 'w'), indent=4)
|
||||
@@ -0,0 +1,52 @@
|
||||
import os
|
||||
import trimesh
|
||||
import numpy as np
|
||||
import argparse
|
||||
import json
|
||||
|
||||
from partcrafter_src.utils.data_utils import scene_to_parts, mesh_to_surface, normalize_mesh
|
||||
|
||||
if __name__ == '__main__':
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument('--input', type=str, default='assets/objects/scissors.glb')
|
||||
parser.add_argument('--output', type=str, default='preprocessed_data')
|
||||
args = parser.parse_args()
|
||||
|
||||
input_path = args.input
|
||||
output_path = args.output
|
||||
|
||||
assert os.path.exists(input_path), f'{input_path} does not exist'
|
||||
|
||||
mesh_name = os.path.basename(input_path).split('.')[0]
|
||||
output_path = os.path.join(output_path, mesh_name)
|
||||
if not os.path.exists(output_path):
|
||||
os.makedirs(output_path)
|
||||
|
||||
config = {
|
||||
"num_parts": 0,
|
||||
}
|
||||
|
||||
# sample points from mesh surface
|
||||
mesh = trimesh.load(input_path, process=False)
|
||||
mesh = normalize_mesh(mesh)
|
||||
config["num_parts"] = len(mesh.geometry)
|
||||
if config["num_parts"] > 1 and config["num_parts"] <= 16:
|
||||
parts = scene_to_parts(
|
||||
mesh,
|
||||
return_type="point",
|
||||
normalize=False
|
||||
)
|
||||
else:
|
||||
parts = []
|
||||
mesh = mesh.to_geometry()
|
||||
object = mesh_to_surface(mesh, return_dict=True)
|
||||
datas = {
|
||||
"object": object,
|
||||
"parts": parts,
|
||||
}
|
||||
# save points
|
||||
np.save(os.path.join(output_path, 'points.npy'), datas)
|
||||
|
||||
# save config
|
||||
with open(os.path.join(output_path, 'num_parts.json'), 'w') as f:
|
||||
json.dump(config, f, indent=4)
|
||||
@@ -0,0 +1,68 @@
|
||||
import os
|
||||
import json
|
||||
import argparse
|
||||
import time
|
||||
from tqdm import tqdm
|
||||
|
||||
if __name__ == '__main__':
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument('--input', type=str, default='assets/objects')
|
||||
parser.add_argument('--output', type=str, default='preprocessed_data')
|
||||
args = parser.parse_args()
|
||||
|
||||
input_path = args.input
|
||||
output_path = args.output
|
||||
|
||||
assert os.path.exists(input_path), f'{input_path} does not exist'
|
||||
|
||||
if not os.path.exists(output_path):
|
||||
os.makedirs(output_path)
|
||||
|
||||
for mesh_name in tqdm(os.listdir(input_path)):
|
||||
mesh_path = os.path.join(input_path, mesh_name)
|
||||
# 1. Sample points from mesh surface
|
||||
os.system(f"python datasets/preprocess/mesh_to_point.py --input {mesh_path} --output {output_path}")
|
||||
# 2. Render images
|
||||
os.system(f"python datasets/preprocess/render.py --input {mesh_path} --output {output_path}")
|
||||
# 3. Remove background for rendered images and resize to 90%
|
||||
export_mesh_folder = os.path.join(output_path, mesh_name.replace('.glb', ''))
|
||||
export_rendering_path = os.path.join(export_mesh_folder, 'rendering.png')
|
||||
os.system(f"python datasets/preprocess/rmbg.py --input {export_rendering_path} --output {output_path}")
|
||||
# 4. (Optional) Calculate IoU
|
||||
os.system(f"python datasets/preprocess/calculate_iou.py --input {mesh_path} --output {output_path}")
|
||||
time.sleep(1)
|
||||
|
||||
# generate configs
|
||||
configs = []
|
||||
for mesh_name in tqdm(os.listdir(input_path)):
|
||||
mesh_path = os.path.join(output_path, mesh_name.replace('.glb', ''))
|
||||
num_parts_path = os.path.join(mesh_path, 'num_parts.json')
|
||||
surface_path = os.path.join(mesh_path, 'points.npy')
|
||||
image_path = os.path.join(mesh_path, 'rendering_rmbg.png')
|
||||
iou_path = os.path.join(mesh_path, 'iou.json')
|
||||
config = {
|
||||
"file": mesh_name,
|
||||
"num_parts": 0,
|
||||
"valid": False,
|
||||
"mesh_path": os.path.join(input_path, mesh_name),
|
||||
"surface_path": None,
|
||||
"image_path": None,
|
||||
"iou_mean": 0.0,
|
||||
"iou_max": 0.0
|
||||
}
|
||||
try:
|
||||
config["num_parts"] = json.load(open(num_parts_path))['num_parts']
|
||||
iou_config = json.load(open(iou_path))
|
||||
config['iou_mean'] = iou_config['iou_mean']
|
||||
config['iou_max'] = iou_config['iou_max']
|
||||
assert os.path.exists(surface_path)
|
||||
config['surface_path'] = surface_path
|
||||
assert os.path.exists(image_path)
|
||||
config['image_path'] = image_path
|
||||
config['valid'] = True
|
||||
configs.append(config)
|
||||
except:
|
||||
continue
|
||||
|
||||
configs_path = os.path.join(output_path, 'object_part_configs.json')
|
||||
json.dump(configs, open(configs_path, 'w'), indent=4)
|
||||
@@ -0,0 +1,41 @@
|
||||
import os
|
||||
import trimesh
|
||||
import numpy as np
|
||||
import argparse
|
||||
import json
|
||||
|
||||
from partcrafter_src.utils.data_utils import normalize_mesh
|
||||
from partcrafter_src.utils.render_utils import render_single_view
|
||||
|
||||
RADIUS = 4
|
||||
IMAGE_SIZE = (2048, 2048)
|
||||
LIGHT_INTENSITY = 2.5
|
||||
NUM_ENV_LIGHTS = 36
|
||||
|
||||
if __name__ == '__main__':
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument('--input', type=str, default='assets/objects/scissors.glb')
|
||||
parser.add_argument('--output', type=str, default='preprocessed_data')
|
||||
args = parser.parse_args()
|
||||
|
||||
input_path = args.input
|
||||
output_path = args.output
|
||||
|
||||
assert os.path.exists(input_path), f'{input_path} does not exist'
|
||||
|
||||
mesh_name = os.path.basename(input_path).split('.')[0]
|
||||
output_path = os.path.join(output_path, mesh_name)
|
||||
if not os.path.exists(output_path):
|
||||
os.makedirs(output_path)
|
||||
|
||||
mesh = normalize_mesh(trimesh.load(input_path, process=False))
|
||||
mesh = mesh.to_geometry()
|
||||
image = render_single_view(
|
||||
mesh,
|
||||
radius=RADIUS,
|
||||
image_size=IMAGE_SIZE,
|
||||
light_intensity=LIGHT_INTENSITY,
|
||||
num_env_lights=NUM_ENV_LIGHTS,
|
||||
return_type='pil'
|
||||
)
|
||||
image.save(os.path.join(output_path, f'rendering.png'))
|
||||
@@ -0,0 +1,33 @@
|
||||
import os
|
||||
import trimesh
|
||||
import numpy as np
|
||||
import argparse
|
||||
import json
|
||||
import torch
|
||||
from huggingface_hub import snapshot_download
|
||||
|
||||
from partcrafter_src.utils.image_utils import prepare_image
|
||||
from partcrafter_src.models.briarmbg import BriaRMBG
|
||||
|
||||
if __name__ == '__main__':
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument('--input', type=str, default='preprocessed_data/scissors/scissors.png')
|
||||
parser.add_argument('--output', type=str, default='preprocessed_data')
|
||||
args = parser.parse_args()
|
||||
|
||||
input_path = args.input
|
||||
output_path = args.output
|
||||
|
||||
assert os.path.exists(input_path), f'{input_path} does not exist'
|
||||
|
||||
mesh_name = os.path.basename(os.path.dirname(input_path))
|
||||
output_path = os.path.join(output_path, mesh_name)
|
||||
if not os.path.exists(output_path):
|
||||
os.makedirs(output_path)
|
||||
|
||||
rmbg_weights_dir = "pretrained_weights/RMBG-1.4"
|
||||
snapshot_download(repo_id="briaai/RMBG-1.4", local_dir=rmbg_weights_dir)
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
rmbg_net = BriaRMBG.from_pretrained(rmbg_weights_dir).to(device)
|
||||
rendering_rmbg = prepare_image(input_path, bg_color=np.array([1.0, 1.0, 1.0]), rmbg_net=rmbg_net, device=device)
|
||||
rendering_rmbg.save(os.path.join(output_path, f'rendering_rmbg.png'))
|
||||
@@ -0,0 +1,51 @@
|
||||
from partcrafter_src.utils.typing_utils import *
|
||||
|
||||
import torch
|
||||
|
||||
from .objaverse_part import ObjaversePartDataset, BatchedObjaversePartDataset
|
||||
|
||||
# Copied from https://github.com/huggingface/pytorch-image-models/blob/main/timm/data/loader.py
|
||||
class MultiEpochsDataLoader(torch.utils.data.DataLoader):
|
||||
|
||||
def __init__(self, *args, **kwargs):
|
||||
super().__init__(*args, **kwargs)
|
||||
self._DataLoader__initialized = False
|
||||
if self.batch_sampler is None:
|
||||
self.sampler = _RepeatSampler(self.sampler)
|
||||
else:
|
||||
self.batch_sampler = _RepeatSampler(self.batch_sampler)
|
||||
self._DataLoader__initialized = True
|
||||
self.iterator = super().__iter__()
|
||||
|
||||
def __len__(self):
|
||||
return len(self.sampler) if self.batch_sampler is None else len(self.batch_sampler.sampler)
|
||||
|
||||
def __iter__(self):
|
||||
for i in range(len(self)):
|
||||
yield next(self.iterator)
|
||||
|
||||
|
||||
class _RepeatSampler(object):
|
||||
""" Sampler that repeats forever.
|
||||
|
||||
Args:
|
||||
sampler (Sampler)
|
||||
"""
|
||||
|
||||
def __init__(self, sampler):
|
||||
self.sampler = sampler
|
||||
if isinstance(self.sampler, torch.utils.data.sampler.BatchSampler):
|
||||
self.batch_size = self.sampler.batch_size
|
||||
self.drop_last = self.sampler.drop_last
|
||||
|
||||
def __len__(self):
|
||||
return len(self.sampler)
|
||||
|
||||
def __iter__(self):
|
||||
while True:
|
||||
yield from iter(self.sampler)
|
||||
|
||||
def yield_forever(iterator: Iterator[Any]):
|
||||
while True:
|
||||
for x in iterator:
|
||||
yield x
|
||||
@@ -0,0 +1,197 @@
|
||||
from partcrafter_src.utils.typing_utils import *
|
||||
|
||||
import json
|
||||
import os
|
||||
import random
|
||||
|
||||
import accelerate
|
||||
import torch
|
||||
from torchvision import transforms
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
from tqdm import tqdm
|
||||
|
||||
from partcrafter_src.utils.data_utils import load_surface, load_surfaces
|
||||
|
||||
class ObjaversePartDataset(torch.utils.data.Dataset):
|
||||
def __init__(
|
||||
self,
|
||||
configs: DictConfig,
|
||||
training: bool = True,
|
||||
):
|
||||
super().__init__()
|
||||
self.configs = configs
|
||||
self.training = training
|
||||
|
||||
self.min_num_parts = configs['dataset']['min_num_parts']
|
||||
self.max_num_parts = configs['dataset']['max_num_parts']
|
||||
self.val_min_num_parts = configs['val']['min_num_parts']
|
||||
self.val_max_num_parts = configs['val']['max_num_parts']
|
||||
|
||||
self.max_iou_mean = configs['dataset'].get('max_iou_mean', None)
|
||||
self.max_iou_max = configs['dataset'].get('max_iou_max', None)
|
||||
|
||||
self.shuffle_parts = configs['dataset']['shuffle_parts']
|
||||
self.training_ratio = configs['dataset']['training_ratio']
|
||||
self.balance_object_and_parts = configs['dataset'].get('balance_object_and_parts', False)
|
||||
|
||||
self.rotating_ratio = configs['dataset'].get('rotating_ratio', 0.0)
|
||||
self.rotating_degree = configs['dataset'].get('rotating_degree', 10.0)
|
||||
self.transform = transforms.Compose([
|
||||
transforms.RandomRotation(degrees=(-self.rotating_degree, self.rotating_degree), fill=(255, 255, 255)),
|
||||
])
|
||||
|
||||
if isinstance(configs['dataset']['config'], ListConfig):
|
||||
data_configs = []
|
||||
for config in configs['dataset']['config']:
|
||||
local_data_configs = json.load(open(config))
|
||||
if self.balance_object_and_parts:
|
||||
if self.training:
|
||||
local_data_configs = local_data_configs[:int(len(local_data_configs) * self.training_ratio)]
|
||||
else:
|
||||
local_data_configs = local_data_configs[int(len(local_data_configs) * self.training_ratio):]
|
||||
local_data_configs = [config for config in local_data_configs if self.val_min_num_parts <= config['num_parts'] <= self.val_max_num_parts]
|
||||
data_configs += local_data_configs
|
||||
else:
|
||||
data_configs = json.load(open(configs['dataset']['config']))
|
||||
data_configs = [config for config in data_configs if config['valid']]
|
||||
data_configs = [config for config in data_configs if self.min_num_parts <= config['num_parts'] <= self.max_num_parts]
|
||||
if self.max_iou_mean is not None and self.max_iou_max is not None:
|
||||
data_configs = [config for config in data_configs if config['iou_mean'] <= self.max_iou_mean]
|
||||
data_configs = [config for config in data_configs if config['iou_max'] <= self.max_iou_max]
|
||||
if not self.balance_object_and_parts:
|
||||
if self.training:
|
||||
data_configs = data_configs[:int(len(data_configs) * self.training_ratio)]
|
||||
else:
|
||||
data_configs = data_configs[int(len(data_configs) * self.training_ratio):]
|
||||
data_configs = [config for config in data_configs if self.val_min_num_parts <= config['num_parts'] <= self.val_max_num_parts]
|
||||
self.data_configs = data_configs
|
||||
self.image_size = (512, 512)
|
||||
|
||||
def __len__(self) -> int:
|
||||
return len(self.data_configs)
|
||||
|
||||
def _get_data_by_config(self, data_config):
|
||||
if 'surface_path' in data_config:
|
||||
surface_path = data_config['surface_path']
|
||||
surface_data = np.load(surface_path, allow_pickle=True).item()
|
||||
# If parts is empty, the object is the only part
|
||||
part_surfaces = surface_data['parts'] if len(surface_data['parts']) > 0 else [surface_data['object']]
|
||||
if self.shuffle_parts:
|
||||
random.shuffle(part_surfaces)
|
||||
part_surfaces = load_surfaces(part_surfaces) # [N, P, 6]
|
||||
else:
|
||||
part_surfaces = []
|
||||
for surface_path in data_config['surface_paths']:
|
||||
surface_data = np.load(surface_path, allow_pickle=True).item()
|
||||
part_surfaces.append(load_surface(surface_data))
|
||||
part_surfaces = torch.stack(part_surfaces, dim=0) # [N, P, 6]
|
||||
image_path = data_config['image_path']
|
||||
image = Image.open(image_path).resize(self.image_size)
|
||||
if random.random() < self.rotating_ratio:
|
||||
image = self.transform(image)
|
||||
image = np.array(image)
|
||||
image = torch.from_numpy(image).to(torch.uint8) # [H, W, 3]
|
||||
images = torch.stack([image] * part_surfaces.shape[0], dim=0) # [N, H, W, 3]
|
||||
return {
|
||||
"images": images,
|
||||
"part_surfaces": part_surfaces,
|
||||
}
|
||||
|
||||
def __getitem__(self, idx: int):
|
||||
# The dataset can only support batchsize == 1 training.
|
||||
# Because the number of parts is not fixed.
|
||||
# Please see BatchedObjaversePartDataset for batched training.
|
||||
data_config = self.data_configs[idx]
|
||||
data = self._get_data_by_config(data_config)
|
||||
return data
|
||||
|
||||
class BatchedObjaversePartDataset(ObjaversePartDataset):
|
||||
def __init__(
|
||||
self,
|
||||
configs: DictConfig,
|
||||
batch_size: int,
|
||||
is_main_process: bool = False,
|
||||
shuffle: bool = True,
|
||||
training: bool = True,
|
||||
):
|
||||
assert training
|
||||
assert batch_size > 1
|
||||
super().__init__(configs, training)
|
||||
self.batch_size = batch_size
|
||||
self.is_main_process = is_main_process
|
||||
if batch_size < self.max_num_parts:
|
||||
self.data_configs = [config for config in self.data_configs if config['num_parts'] <= batch_size]
|
||||
|
||||
if shuffle:
|
||||
random.shuffle(self.data_configs)
|
||||
|
||||
self.object_configs = [config for config in self.data_configs if config['num_parts'] == 1]
|
||||
self.parts_configs = [config for config in self.data_configs if config['num_parts'] > 1]
|
||||
|
||||
self.object_ratio = configs['dataset']['object_ratio']
|
||||
# Here we keep the ratio of object to parts
|
||||
self.object_configs = self.object_configs[:int(len(self.parts_configs) * self.object_ratio)]
|
||||
|
||||
dropped_data_configs = self.parts_configs + self.object_configs
|
||||
if shuffle:
|
||||
random.shuffle(dropped_data_configs)
|
||||
|
||||
self.data_configs = self._get_batched_configs(dropped_data_configs, batch_size)
|
||||
|
||||
def _get_batched_configs(self, data_configs, batch_size):
|
||||
batched_data_configs = []
|
||||
num_data_configs = len(data_configs)
|
||||
progress_bar = tqdm(
|
||||
range(len(data_configs)),
|
||||
desc="Batching Dataset",
|
||||
ncols=125,
|
||||
disable=not self.is_main_process,
|
||||
)
|
||||
while len(data_configs) > 0:
|
||||
temp_batch = []
|
||||
temp_num_parts = 0
|
||||
unchosen_configs = []
|
||||
while temp_num_parts < batch_size and len(data_configs) > 0:
|
||||
config = data_configs.pop() # pop the last config
|
||||
num_parts = config['num_parts']
|
||||
if temp_num_parts + num_parts <= batch_size:
|
||||
temp_batch.append(config)
|
||||
temp_num_parts += num_parts
|
||||
progress_bar.update(1)
|
||||
else:
|
||||
unchosen_configs.append(config) # add back to the end
|
||||
data_configs = data_configs + unchosen_configs # concat the unchosen configs
|
||||
if temp_num_parts == batch_size:
|
||||
# Successfully get a batch
|
||||
if len(temp_batch) < batch_size:
|
||||
# pad the batch
|
||||
temp_batch += [{}] * (batch_size - len(temp_batch))
|
||||
batched_data_configs += temp_batch
|
||||
# Else, the code enters here because len(data_configs) == 0
|
||||
# which means in the left data_configs, there are no enough
|
||||
# "suitable" configs to form a batch.
|
||||
# Thus, drop the uncompleted batch.
|
||||
progress_bar.close()
|
||||
return batched_data_configs
|
||||
|
||||
def __getitem__(self, idx: int):
|
||||
data_config = self.data_configs[idx]
|
||||
if len(data_config) == 0:
|
||||
# placeholder
|
||||
return {}
|
||||
data = self._get_data_by_config(data_config)
|
||||
return data
|
||||
|
||||
def collate_fn(self, batch):
|
||||
batch = [data for data in batch if len(data) > 0]
|
||||
images = torch.cat([data['images'] for data in batch], dim=0) # [N, H, W, 3]
|
||||
surfaces = torch.cat([data['part_surfaces'] for data in batch], dim=0) # [N, P, 6]
|
||||
num_parts = torch.LongTensor([data['part_surfaces'].shape[0] for data in batch])
|
||||
assert images.shape[0] == surfaces.shape[0] == num_parts.sum() == self.batch_size
|
||||
batch = {
|
||||
"images": images,
|
||||
"part_surfaces": surfaces,
|
||||
"num_parts": num_parts,
|
||||
}
|
||||
return batch
|
||||
@@ -0,0 +1,624 @@
|
||||
from typing import Callable, List, Optional, Tuple, Union
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from diffusers.models.attention_processor import Attention
|
||||
from diffusers.utils import logging
|
||||
from diffusers.utils.import_utils import is_torch_npu_available, is_xformers_available
|
||||
from diffusers.utils.torch_utils import is_torch_version, maybe_allow_in_graph
|
||||
from einops import rearrange
|
||||
from torch import nn
|
||||
|
||||
logger = logging.get_logger(__name__) # pylint: disable=invalid-name
|
||||
|
||||
class FlashTripo2AttnProcessor2_0:
|
||||
r"""
|
||||
Processor for implementing scaled dot-product attention (enabled by default if you're using PyTorch 2.0). This is
|
||||
used in the Tripo2DiT model. It applies a s normalization layer and rotary embedding on query and key vector.
|
||||
"""
|
||||
|
||||
def __init__(self, topk=True):
|
||||
if not hasattr(F, "scaled_dot_product_attention"):
|
||||
raise ImportError(
|
||||
"AttnProcessor2_0 requires PyTorch 2.0, to use it, please upgrade PyTorch to 2.0."
|
||||
)
|
||||
self.topk = topk
|
||||
|
||||
def qkv(self, attn, q, k, v, attn_mask, dropout_p, is_causal):
|
||||
if k.shape[-2] == 3072:
|
||||
topk = 1024
|
||||
elif k.shape[-2] == 512:
|
||||
topk = 256
|
||||
else:
|
||||
topk = k.shape[-2] // 3
|
||||
|
||||
if self.topk is True:
|
||||
q1 = q[:, :, ::100, :]
|
||||
sim = q1 @ k.transpose(-1, -2)
|
||||
sim = torch.mean(sim, -2)
|
||||
topk_ind = torch.topk(sim, dim=-1, k=topk).indices.squeeze(-2).unsqueeze(-1)
|
||||
topk_ind = topk_ind.expand(-1, -1, -1, v.shape[-1])
|
||||
v0 = torch.gather(v, dim=-2, index=topk_ind)
|
||||
k0 = torch.gather(k, dim=-2, index=topk_ind)
|
||||
out = F.scaled_dot_product_attention(q, k0, v0)
|
||||
elif self.topk is False:
|
||||
out = F.scaled_dot_product_attention(q, k, v)
|
||||
else:
|
||||
idx, counts = self.topk
|
||||
start = 0
|
||||
outs = []
|
||||
for grid_coord, count in zip(idx, counts):
|
||||
end = start + count
|
||||
q_chunk = q[:, :, start:end, :]
|
||||
q1 = q_chunk[:, :, ::50, :]
|
||||
sim = q1 @ k.transpose(-1, -2)
|
||||
sim = torch.mean(sim, -2)
|
||||
topk_ind = torch.topk(sim, dim=-1, k=topk).indices.squeeze(-2).unsqueeze(-1)
|
||||
topk_ind = topk_ind.expand(-1, -1, -1, v.shape[-1])
|
||||
v0 = torch.gather(v, dim=-2, index=topk_ind)
|
||||
k0 = torch.gather(k, dim=-2, index=topk_ind)
|
||||
out = F.scaled_dot_product_attention(q_chunk, k0, v0)
|
||||
outs.append(out)
|
||||
start += count
|
||||
out = torch.cat(outs, dim=-2)
|
||||
self.topk = False
|
||||
return out
|
||||
|
||||
def __call__(
|
||||
self,
|
||||
attn: Attention,
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: Optional[torch.Tensor] = None,
|
||||
attention_mask: Optional[torch.Tensor] = None,
|
||||
temb: Optional[torch.Tensor] = None,
|
||||
image_rotary_emb: Optional[torch.Tensor] = None,
|
||||
) -> torch.Tensor:
|
||||
from diffusers.models.embeddings import apply_rotary_emb
|
||||
|
||||
residual = hidden_states
|
||||
if attn.spatial_norm is not None:
|
||||
hidden_states = attn.spatial_norm(hidden_states, temb)
|
||||
|
||||
input_ndim = hidden_states.ndim
|
||||
|
||||
if input_ndim == 4:
|
||||
batch_size, channel, height, width = hidden_states.shape
|
||||
hidden_states = hidden_states.view(
|
||||
batch_size, channel, height * width
|
||||
).transpose(1, 2)
|
||||
|
||||
batch_size, sequence_length, _ = (
|
||||
hidden_states.shape
|
||||
if encoder_hidden_states is None
|
||||
else encoder_hidden_states.shape
|
||||
)
|
||||
|
||||
if attention_mask is not None:
|
||||
attention_mask = attn.prepare_attention_mask(
|
||||
attention_mask, sequence_length, batch_size
|
||||
)
|
||||
# scaled_dot_product_attention expects attention_mask shape to be
|
||||
# (batch, heads, source_length, target_length)
|
||||
attention_mask = attention_mask.view(
|
||||
batch_size, attn.heads, -1, attention_mask.shape[-1]
|
||||
)
|
||||
|
||||
if attn.group_norm is not None:
|
||||
hidden_states = attn.group_norm(hidden_states.transpose(1, 2)).transpose(
|
||||
1, 2
|
||||
)
|
||||
|
||||
query = attn.to_q(hidden_states)
|
||||
|
||||
if encoder_hidden_states is None:
|
||||
encoder_hidden_states = hidden_states
|
||||
elif attn.norm_cross:
|
||||
encoder_hidden_states = attn.norm_encoder_hidden_states(
|
||||
encoder_hidden_states
|
||||
)
|
||||
|
||||
key = attn.to_k(encoder_hidden_states)
|
||||
value = attn.to_v(encoder_hidden_states)
|
||||
|
||||
# NOTE that tripo2 split heads first then split qkv or kv, like .view(..., attn.heads, 3, dim)
|
||||
# instead of .view(..., 3, attn.heads, dim). So we need to re-split here.
|
||||
if not attn.is_cross_attention:
|
||||
qkv = torch.cat((query, key, value), dim=-1)
|
||||
split_size = qkv.shape[-1] // attn.heads // 3
|
||||
qkv = qkv.view(batch_size, -1, attn.heads, split_size * 3)
|
||||
query, key, value = torch.split(qkv, split_size, dim=-1)
|
||||
else:
|
||||
kv = torch.cat((key, value), dim=-1)
|
||||
split_size = kv.shape[-1] // attn.heads // 2
|
||||
kv = kv.view(batch_size, -1, attn.heads, split_size * 2)
|
||||
key, value = torch.split(kv, split_size, dim=-1)
|
||||
|
||||
head_dim = key.shape[-1]
|
||||
|
||||
query = query.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
key = key.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
value = value.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
if attn.norm_q is not None:
|
||||
query = attn.norm_q(query)
|
||||
if attn.norm_k is not None:
|
||||
key = attn.norm_k(key)
|
||||
|
||||
# Apply RoPE if needed
|
||||
if image_rotary_emb is not None:
|
||||
query = apply_rotary_emb(query, image_rotary_emb)
|
||||
if not attn.is_cross_attention:
|
||||
key = apply_rotary_emb(key, image_rotary_emb)
|
||||
|
||||
# flashvdm topk
|
||||
hidden_states = self.qkv(attn, query, key, value, attn_mask=attention_mask, dropout_p=0.0, is_causal=False)
|
||||
|
||||
hidden_states = hidden_states.transpose(1, 2).reshape(
|
||||
batch_size, -1, attn.heads * head_dim
|
||||
)
|
||||
hidden_states = hidden_states.to(query.dtype)
|
||||
|
||||
# linear proj
|
||||
hidden_states = attn.to_out[0](hidden_states)
|
||||
# dropout
|
||||
hidden_states = attn.to_out[1](hidden_states)
|
||||
|
||||
if input_ndim == 4:
|
||||
hidden_states = hidden_states.transpose(-1, -2).reshape(
|
||||
batch_size, channel, height, width
|
||||
)
|
||||
|
||||
if attn.residual_connection:
|
||||
hidden_states = hidden_states + residual
|
||||
|
||||
hidden_states = hidden_states / attn.rescale_output_factor
|
||||
|
||||
return hidden_states
|
||||
|
||||
class TripoSGAttnProcessor2_0:
|
||||
r"""
|
||||
Processor for implementing scaled dot-product attention (enabled by default if you're using PyTorch 2.0). This is
|
||||
used in the TripoSG model. It applies a s normalization layer and rotary embedding on query and key vector.
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
if not hasattr(F, "scaled_dot_product_attention"):
|
||||
raise ImportError(
|
||||
"AttnProcessor2_0 requires PyTorch 2.0, to use it, please upgrade PyTorch to 2.0."
|
||||
)
|
||||
|
||||
def __call__(
|
||||
self,
|
||||
attn: Attention,
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: Optional[torch.Tensor] = None,
|
||||
attention_mask: Optional[torch.Tensor] = None,
|
||||
temb: Optional[torch.Tensor] = None,
|
||||
image_rotary_emb: Optional[torch.Tensor] = None,
|
||||
) -> torch.Tensor:
|
||||
from diffusers.models.embeddings import apply_rotary_emb
|
||||
|
||||
residual = hidden_states
|
||||
if attn.spatial_norm is not None:
|
||||
hidden_states = attn.spatial_norm(hidden_states, temb)
|
||||
|
||||
input_ndim = hidden_states.ndim
|
||||
|
||||
if input_ndim == 4:
|
||||
batch_size, channel, height, width = hidden_states.shape
|
||||
hidden_states = hidden_states.view(
|
||||
batch_size, channel, height * width
|
||||
).transpose(1, 2)
|
||||
|
||||
batch_size, sequence_length, _ = (
|
||||
hidden_states.shape
|
||||
if encoder_hidden_states is None
|
||||
else encoder_hidden_states.shape
|
||||
)
|
||||
|
||||
if attention_mask is not None:
|
||||
attention_mask = attn.prepare_attention_mask(
|
||||
attention_mask, sequence_length, batch_size
|
||||
)
|
||||
# scaled_dot_product_attention expects attention_mask shape to be
|
||||
# (batch, heads, source_length, target_length)
|
||||
attention_mask = attention_mask.view(
|
||||
batch_size, attn.heads, -1, attention_mask.shape[-1]
|
||||
)
|
||||
|
||||
if attn.group_norm is not None:
|
||||
hidden_states = attn.group_norm(hidden_states.transpose(1, 2)).transpose(
|
||||
1, 2
|
||||
)
|
||||
|
||||
query = attn.to_q(hidden_states)
|
||||
|
||||
if encoder_hidden_states is None:
|
||||
encoder_hidden_states = hidden_states
|
||||
elif attn.norm_cross:
|
||||
encoder_hidden_states = attn.norm_encoder_hidden_states(
|
||||
encoder_hidden_states
|
||||
)
|
||||
|
||||
key = attn.to_k(encoder_hidden_states)
|
||||
value = attn.to_v(encoder_hidden_states)
|
||||
|
||||
# NOTE that pre-trained models split heads first then split qkv or kv, like .view(..., attn.heads, 3, dim)
|
||||
# instead of .view(..., 3, attn.heads, dim). So we need to re-split here.
|
||||
if not attn.is_cross_attention:
|
||||
qkv = torch.cat((query, key, value), dim=-1)
|
||||
split_size = qkv.shape[-1] // attn.heads // 3
|
||||
qkv = qkv.view(batch_size, -1, attn.heads, split_size * 3)
|
||||
query, key, value = torch.split(qkv, split_size, dim=-1)
|
||||
else:
|
||||
kv = torch.cat((key, value), dim=-1)
|
||||
split_size = kv.shape[-1] // attn.heads // 2
|
||||
kv = kv.view(batch_size, -1, attn.heads, split_size * 2)
|
||||
key, value = torch.split(kv, split_size, dim=-1)
|
||||
|
||||
head_dim = key.shape[-1]
|
||||
|
||||
query = query.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
key = key.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
value = value.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
if attn.norm_q is not None:
|
||||
query = attn.norm_q(query)
|
||||
if attn.norm_k is not None:
|
||||
key = attn.norm_k(key)
|
||||
|
||||
# Apply RoPE if needed
|
||||
if image_rotary_emb is not None:
|
||||
query = apply_rotary_emb(query, image_rotary_emb)
|
||||
if not attn.is_cross_attention:
|
||||
key = apply_rotary_emb(key, image_rotary_emb)
|
||||
|
||||
# the output of sdp = (batch, num_heads, seq_len, head_dim)
|
||||
# TODO: add support for attn.scale when we move to Torch 2.1
|
||||
hidden_states = F.scaled_dot_product_attention(
|
||||
query, key, value, attn_mask=attention_mask, dropout_p=0.0, is_causal=False
|
||||
)
|
||||
|
||||
hidden_states = hidden_states.transpose(1, 2).reshape(
|
||||
batch_size, -1, attn.heads * head_dim
|
||||
)
|
||||
hidden_states = hidden_states.to(query.dtype)
|
||||
|
||||
# linear proj
|
||||
hidden_states = attn.to_out[0](hidden_states)
|
||||
# dropout
|
||||
hidden_states = attn.to_out[1](hidden_states)
|
||||
|
||||
if input_ndim == 4:
|
||||
hidden_states = hidden_states.transpose(-1, -2).reshape(
|
||||
batch_size, channel, height, width
|
||||
)
|
||||
|
||||
if attn.residual_connection:
|
||||
hidden_states = hidden_states + residual
|
||||
|
||||
hidden_states = hidden_states / attn.rescale_output_factor
|
||||
|
||||
return hidden_states
|
||||
|
||||
|
||||
class FusedTripoSGAttnProcessor2_0:
|
||||
r"""
|
||||
Processor for implementing scaled dot-product attention (enabled by default if you're using PyTorch 2.0) with fused
|
||||
projection layers. This is used in the HunyuanDiT model. It applies a s normalization layer and rotary embedding on
|
||||
query and key vector.
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
if not hasattr(F, "scaled_dot_product_attention"):
|
||||
raise ImportError(
|
||||
"FusedTripoSGAttnProcessor2_0 requires PyTorch 2.0, to use it, please upgrade PyTorch to 2.0."
|
||||
)
|
||||
|
||||
def __call__(
|
||||
self,
|
||||
attn: Attention,
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: Optional[torch.Tensor] = None,
|
||||
attention_mask: Optional[torch.Tensor] = None,
|
||||
temb: Optional[torch.Tensor] = None,
|
||||
image_rotary_emb: Optional[torch.Tensor] = None,
|
||||
) -> torch.Tensor:
|
||||
from diffusers.models.embeddings import apply_rotary_emb
|
||||
|
||||
residual = hidden_states
|
||||
if attn.spatial_norm is not None:
|
||||
hidden_states = attn.spatial_norm(hidden_states, temb)
|
||||
|
||||
input_ndim = hidden_states.ndim
|
||||
|
||||
if input_ndim == 4:
|
||||
batch_size, channel, height, width = hidden_states.shape
|
||||
hidden_states = hidden_states.view(
|
||||
batch_size, channel, height * width
|
||||
).transpose(1, 2)
|
||||
|
||||
batch_size, sequence_length, _ = (
|
||||
hidden_states.shape
|
||||
if encoder_hidden_states is None
|
||||
else encoder_hidden_states.shape
|
||||
)
|
||||
|
||||
if attention_mask is not None:
|
||||
attention_mask = attn.prepare_attention_mask(
|
||||
attention_mask, sequence_length, batch_size
|
||||
)
|
||||
# scaled_dot_product_attention expects attention_mask shape to be
|
||||
# (batch, heads, source_length, target_length)
|
||||
attention_mask = attention_mask.view(
|
||||
batch_size, attn.heads, -1, attention_mask.shape[-1]
|
||||
)
|
||||
|
||||
if attn.group_norm is not None:
|
||||
hidden_states = attn.group_norm(hidden_states.transpose(1, 2)).transpose(
|
||||
1, 2
|
||||
)
|
||||
|
||||
# NOTE that pre-trained split heads first, then split qkv
|
||||
if encoder_hidden_states is None:
|
||||
qkv = attn.to_qkv(hidden_states)
|
||||
split_size = qkv.shape[-1] // attn.heads // 3
|
||||
qkv = qkv.view(batch_size, -1, attn.heads, split_size * 3)
|
||||
query, key, value = torch.split(qkv, split_size, dim=-1)
|
||||
else:
|
||||
if attn.norm_cross:
|
||||
encoder_hidden_states = attn.norm_encoder_hidden_states(
|
||||
encoder_hidden_states
|
||||
)
|
||||
query = attn.to_q(hidden_states)
|
||||
|
||||
kv = attn.to_kv(encoder_hidden_states)
|
||||
split_size = kv.shape[-1] // attn.heads // 2
|
||||
kv = kv.view(batch_size, -1, attn.heads, split_size * 2)
|
||||
key, value = torch.split(kv, split_size, dim=-1)
|
||||
|
||||
head_dim = key.shape[-1]
|
||||
|
||||
query = query.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
key = key.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
value = value.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
if attn.norm_q is not None:
|
||||
query = attn.norm_q(query)
|
||||
if attn.norm_k is not None:
|
||||
key = attn.norm_k(key)
|
||||
|
||||
# Apply RoPE if needed
|
||||
if image_rotary_emb is not None:
|
||||
query = apply_rotary_emb(query, image_rotary_emb)
|
||||
if not attn.is_cross_attention:
|
||||
key = apply_rotary_emb(key, image_rotary_emb)
|
||||
|
||||
# the output of sdp = (batch, num_heads, seq_len, head_dim)
|
||||
# TODO: add support for attn.scale when we move to Torch 2.1
|
||||
hidden_states = F.scaled_dot_product_attention(
|
||||
query, key, value, attn_mask=attention_mask, dropout_p=0.0, is_causal=False
|
||||
)
|
||||
|
||||
hidden_states = hidden_states.transpose(1, 2).reshape(
|
||||
batch_size, -1, attn.heads * head_dim
|
||||
)
|
||||
hidden_states = hidden_states.to(query.dtype)
|
||||
|
||||
# linear proj
|
||||
hidden_states = attn.to_out[0](hidden_states)
|
||||
# dropout
|
||||
hidden_states = attn.to_out[1](hidden_states)
|
||||
|
||||
if input_ndim == 4:
|
||||
hidden_states = hidden_states.transpose(-1, -2).reshape(
|
||||
batch_size, channel, height, width
|
||||
)
|
||||
|
||||
if attn.residual_connection:
|
||||
hidden_states = hidden_states + residual
|
||||
|
||||
hidden_states = hidden_states / attn.rescale_output_factor
|
||||
|
||||
return hidden_states
|
||||
|
||||
# Modified from https://github.com/VAST-AI-Research/MIDI-3D/blob/main/midi/models/attention_processor.py#L264
|
||||
class PartCrafterAttnProcessor:
|
||||
r"""
|
||||
Processor for implementing scaled dot-product attention (enabled by default if you're using PyTorch 2.0). This is
|
||||
used in the PartCrafter model. It applies a normalization layer and rotary embedding on query and key vector.
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
if not hasattr(F, "scaled_dot_product_attention"):
|
||||
raise ImportError(
|
||||
"AttnProcessor2_0 requires PyTorch 2.0, to use it, please upgrade PyTorch to 2.0."
|
||||
)
|
||||
|
||||
|
||||
def __call__(
|
||||
self,
|
||||
attn: Attention,
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: Optional[torch.Tensor] = None,
|
||||
attention_mask: Optional[torch.Tensor] = None,
|
||||
temb: Optional[torch.Tensor] = None,
|
||||
image_rotary_emb: Optional[torch.Tensor] = None,
|
||||
num_parts: Optional[Union[int, torch.Tensor]] = None,
|
||||
) -> torch.Tensor:
|
||||
from diffusers.models.embeddings import apply_rotary_emb
|
||||
|
||||
residual = hidden_states
|
||||
if attn.spatial_norm is not None:
|
||||
hidden_states = attn.spatial_norm(hidden_states, temb)
|
||||
|
||||
input_ndim = hidden_states.ndim
|
||||
|
||||
if input_ndim == 4:
|
||||
batch_size, channel, height, width = hidden_states.shape
|
||||
hidden_states = hidden_states.view(
|
||||
batch_size, channel, height * width
|
||||
).transpose(1, 2)
|
||||
|
||||
batch_size, sequence_length, _ = (
|
||||
hidden_states.shape
|
||||
if encoder_hidden_states is None
|
||||
else encoder_hidden_states.shape
|
||||
)
|
||||
|
||||
if attention_mask is not None:
|
||||
attention_mask = attn.prepare_attention_mask(
|
||||
attention_mask, sequence_length, batch_size
|
||||
)
|
||||
# scaled_dot_product_attention expects attention_mask shape to be
|
||||
# (batch, heads, source_length, target_length)
|
||||
attention_mask = attention_mask.view(
|
||||
batch_size, attn.heads, -1, attention_mask.shape[-1]
|
||||
)
|
||||
|
||||
if attn.group_norm is not None:
|
||||
hidden_states = attn.group_norm(hidden_states.transpose(1, 2)).transpose(
|
||||
1, 2
|
||||
)
|
||||
|
||||
query = attn.to_q(hidden_states)
|
||||
|
||||
if encoder_hidden_states is None:
|
||||
encoder_hidden_states = hidden_states
|
||||
elif attn.norm_cross:
|
||||
encoder_hidden_states = attn.norm_encoder_hidden_states(
|
||||
encoder_hidden_states
|
||||
)
|
||||
|
||||
key = attn.to_k(encoder_hidden_states)
|
||||
value = attn.to_v(encoder_hidden_states)
|
||||
|
||||
# NOTE that pre-trained models split heads first then split qkv or kv, like .view(..., attn.heads, 3, dim)
|
||||
# instead of .view(..., 3, attn.heads, dim). So we need to re-split here.
|
||||
if not attn.is_cross_attention:
|
||||
qkv = torch.cat((query, key, value), dim=-1)
|
||||
split_size = qkv.shape[-1] // attn.heads // 3
|
||||
qkv = qkv.view(batch_size, -1, attn.heads, split_size * 3)
|
||||
query, key, value = torch.split(qkv, split_size, dim=-1)
|
||||
else:
|
||||
kv = torch.cat((key, value), dim=-1)
|
||||
split_size = kv.shape[-1] // attn.heads // 2
|
||||
kv = kv.view(batch_size, -1, attn.heads, split_size * 2)
|
||||
key, value = torch.split(kv, split_size, dim=-1)
|
||||
|
||||
head_dim = key.shape[-1]
|
||||
|
||||
query = query.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
key = key.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
value = value.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
if attn.norm_q is not None:
|
||||
query = attn.norm_q(query)
|
||||
if attn.norm_k is not None:
|
||||
key = attn.norm_k(key)
|
||||
|
||||
# Apply RoPE if needed
|
||||
if image_rotary_emb is not None:
|
||||
query = apply_rotary_emb(query, image_rotary_emb)
|
||||
if not attn.is_cross_attention:
|
||||
key = apply_rotary_emb(key, image_rotary_emb)
|
||||
|
||||
if isinstance(num_parts, torch.Tensor):
|
||||
# Assume list in training, do not consider classifier-free guidance
|
||||
idx = 0
|
||||
hidden_states_list = []
|
||||
for n_p in num_parts:
|
||||
k = key[idx : idx + n_p]
|
||||
v = value[idx : idx + n_p]
|
||||
q = query[idx : idx + n_p]
|
||||
idx += n_p
|
||||
if k.shape[2] == q.shape[2]:
|
||||
# Assuming self-attention
|
||||
# Here 'b' is always 1
|
||||
k = rearrange(
|
||||
k, "(b ni) h nt c -> b h (ni nt) c", ni=n_p
|
||||
) # [b, h, ni*nt, c]
|
||||
v = rearrange(
|
||||
v, "(b ni) h nt c -> b h (ni nt) c", ni=n_p
|
||||
) # [b, h, ni*nt, c]
|
||||
else:
|
||||
# Assuming cross-attention
|
||||
# Here 'b' is always 1
|
||||
k = k[::n_p] # [b, h, nt, c]
|
||||
v = v[::n_p] # [b, h, nt, c]
|
||||
# Here 'b' is always 1
|
||||
q = rearrange(
|
||||
q, "(b ni) h nt c -> b h (ni nt) c", ni=n_p
|
||||
) # [b, h, ni*nt, c]
|
||||
# the output of sdp = (batch, num_heads, seq_len, head_dim)
|
||||
h_s = F.scaled_dot_product_attention(
|
||||
q, k, v,
|
||||
dropout_p=0.0,
|
||||
is_causal=False,
|
||||
)
|
||||
h_s = h_s.transpose(1, 2).reshape(
|
||||
n_p, -1, attn.heads * head_dim
|
||||
)
|
||||
h_s = h_s.to(query.dtype)
|
||||
hidden_states_list.append(h_s)
|
||||
hidden_states = torch.cat(hidden_states_list, dim=0)
|
||||
|
||||
elif isinstance(num_parts, int):
|
||||
# Assume single instance
|
||||
if key.shape[2] == query.shape[2]:
|
||||
# Assuming self-attention
|
||||
# Here we need 'b' when using classifier-free guidance
|
||||
key = rearrange(
|
||||
key, "(b ni) h nt c -> b h (ni nt) c", ni=num_parts
|
||||
) # [b, h, ni*nt, c]
|
||||
value = rearrange(
|
||||
value, "(b ni) h nt c -> b h (ni nt) c", ni=num_parts
|
||||
) # [b, h, ni*nt, c]
|
||||
else:
|
||||
# Assuming cross-attention
|
||||
# Here we need 'b' when using classifier-free guidance
|
||||
# Control signal is repeated ni times within each (b, ni)
|
||||
# We select only the first instance per group
|
||||
key = key[::num_parts] # [b, h, nt, c]
|
||||
value = value[::num_parts] # [b, h, nt, c]
|
||||
query = rearrange(
|
||||
query, "(b ni) h nt c -> b h (ni nt) c", ni=num_parts
|
||||
) # [b, h, ni*nt, c]
|
||||
|
||||
# the output of sdp = (batch, num_heads, seq_len, head_dim)
|
||||
hidden_states = F.scaled_dot_product_attention(
|
||||
query,
|
||||
key,
|
||||
value,
|
||||
dropout_p=0.0,
|
||||
is_causal=False,
|
||||
)
|
||||
hidden_states = hidden_states.transpose(1, 2).reshape(
|
||||
batch_size, -1, attn.heads * head_dim
|
||||
)
|
||||
hidden_states = hidden_states.to(query.dtype)
|
||||
|
||||
else:
|
||||
raise ValueError(
|
||||
"num_parts must be a torch.Tensor or int, but got {}".format(type(num_parts))
|
||||
)
|
||||
|
||||
# linear proj
|
||||
hidden_states = attn.to_out[0](hidden_states)
|
||||
# dropout
|
||||
hidden_states = attn.to_out[1](hidden_states)
|
||||
|
||||
if input_ndim == 4:
|
||||
hidden_states = hidden_states.transpose(-1, -2).reshape(
|
||||
batch_size, channel, height, width
|
||||
)
|
||||
|
||||
if attn.residual_connection:
|
||||
hidden_states = hidden_states + residual
|
||||
|
||||
hidden_states = hidden_states / attn.rescale_output_factor
|
||||
|
||||
return hidden_states
|
||||
@@ -0,0 +1 @@
|
||||
from .autoencoder_kl_triposg import TripoSGVAEModel
|
||||
+682
@@ -0,0 +1,682 @@
|
||||
from typing import Dict, List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from diffusers.configuration_utils import ConfigMixin, register_to_config
|
||||
from diffusers.models.attention_processor import Attention, AttentionProcessor
|
||||
from diffusers.models.autoencoders.vae import DecoderOutput
|
||||
from diffusers.models.modeling_outputs import AutoencoderKLOutput
|
||||
from diffusers.models.modeling_utils import ModelMixin
|
||||
from diffusers.models.normalization import FP32LayerNorm, LayerNorm
|
||||
from diffusers.utils import logging
|
||||
from diffusers.utils.accelerate_utils import apply_forward_hook
|
||||
from einops import repeat
|
||||
from tqdm import tqdm
|
||||
|
||||
# Check torch_cluster availability
|
||||
try:
|
||||
from torch_cluster import fps
|
||||
TORCH_CLUSTER_AVAILABLE = True
|
||||
print("torch_cluster available - using original FPS sampling method")
|
||||
except ImportError:
|
||||
TORCH_CLUSTER_AVAILABLE = False
|
||||
print("torch_cluster not available - using pytorch3d FPS sampling method")
|
||||
fps = None
|
||||
|
||||
from ..attention_processor import FusedTripoSGAttnProcessor2_0, TripoSGAttnProcessor2_0, FlashTripo2AttnProcessor2_0
|
||||
from ..embeddings import FrequencyPositionalEmbedding
|
||||
from ..transformers.partcrafter_transformer import DiTBlock
|
||||
from .vae import DiagonalGaussianDistribution
|
||||
from pytorch3d.ops import sample_farthest_points
|
||||
|
||||
|
||||
logger = logging.get_logger(__name__) # pylint: disable=invalid-name
|
||||
|
||||
|
||||
class TripoSGEncoder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
in_channels: int = 3,
|
||||
dim: int = 512,
|
||||
num_attention_heads: int = 8,
|
||||
num_layers: int = 8,
|
||||
):
|
||||
super().__init__()
|
||||
|
||||
self.proj_in = nn.Linear(in_channels, dim, bias=True)
|
||||
|
||||
self.blocks = nn.ModuleList(
|
||||
[
|
||||
DiTBlock(
|
||||
dim=dim,
|
||||
num_attention_heads=num_attention_heads,
|
||||
use_self_attention=False,
|
||||
use_cross_attention=True,
|
||||
cross_attention_dim=dim,
|
||||
cross_attention_norm_type="layer_norm",
|
||||
activation_fn="gelu",
|
||||
norm_type="fp32_layer_norm",
|
||||
norm_eps=1e-5,
|
||||
qk_norm=False,
|
||||
qkv_bias=False,
|
||||
) # cross attention
|
||||
]
|
||||
+ [
|
||||
DiTBlock(
|
||||
dim=dim,
|
||||
num_attention_heads=num_attention_heads,
|
||||
use_self_attention=True,
|
||||
self_attention_norm_type="fp32_layer_norm",
|
||||
use_cross_attention=False,
|
||||
activation_fn="gelu",
|
||||
norm_type="fp32_layer_norm",
|
||||
norm_eps=1e-5,
|
||||
qk_norm=False,
|
||||
qkv_bias=False,
|
||||
)
|
||||
for _ in range(num_layers) # self attention
|
||||
]
|
||||
)
|
||||
|
||||
self.norm_out = LayerNorm(dim)
|
||||
|
||||
|
||||
|
||||
|
||||
def forward(self, sample_1: torch.Tensor, sample_2: torch.Tensor):
|
||||
hidden_states = self.proj_in(sample_1)
|
||||
encoder_hidden_states = self.proj_in(sample_2)
|
||||
|
||||
for layer, block in enumerate(self.blocks):
|
||||
if layer == 0:
|
||||
hidden_states = block(
|
||||
hidden_states, encoder_hidden_states=encoder_hidden_states
|
||||
)
|
||||
else:
|
||||
hidden_states = block(hidden_states)
|
||||
|
||||
hidden_states = self.norm_out(hidden_states)
|
||||
|
||||
return hidden_states
|
||||
|
||||
|
||||
class TripoSGDecoder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
in_channels: int = 3,
|
||||
out_channels: int = 1,
|
||||
dim: int = 512,
|
||||
num_attention_heads: int = 8,
|
||||
num_layers: int = 16,
|
||||
grad_type: str = "analytical",
|
||||
grad_interval: float = 0.001,
|
||||
):
|
||||
super().__init__()
|
||||
|
||||
if grad_type not in ["numerical", "analytical"]:
|
||||
raise ValueError(f"grad_type must be one of ['numerical', 'analytical']")
|
||||
self.grad_type = grad_type
|
||||
self.grad_interval = grad_interval
|
||||
|
||||
self.blocks = nn.ModuleList(
|
||||
[
|
||||
DiTBlock(
|
||||
dim=dim,
|
||||
num_attention_heads=num_attention_heads,
|
||||
use_self_attention=True,
|
||||
self_attention_norm_type="fp32_layer_norm",
|
||||
use_cross_attention=False,
|
||||
activation_fn="gelu",
|
||||
norm_type="fp32_layer_norm",
|
||||
norm_eps=1e-5,
|
||||
qk_norm=False,
|
||||
qkv_bias=False,
|
||||
)
|
||||
for _ in range(num_layers) # self attention
|
||||
]
|
||||
+ [
|
||||
DiTBlock(
|
||||
dim=dim,
|
||||
num_attention_heads=num_attention_heads,
|
||||
use_self_attention=False,
|
||||
use_cross_attention=True,
|
||||
cross_attention_dim=dim,
|
||||
cross_attention_norm_type="layer_norm",
|
||||
activation_fn="gelu",
|
||||
norm_type="fp32_layer_norm",
|
||||
norm_eps=1e-5,
|
||||
qk_norm=False,
|
||||
qkv_bias=False,
|
||||
) # cross attention
|
||||
]
|
||||
)
|
||||
|
||||
self.proj_query = nn.Linear(in_channels, dim, bias=True)
|
||||
|
||||
self.norm_out = LayerNorm(dim)
|
||||
self.proj_out = nn.Linear(dim, out_channels, bias=True)
|
||||
|
||||
def set_topk(self, topk):
|
||||
self.blocks[-1].set_topk(topk)
|
||||
|
||||
def set_flash_processor(self, processor):
|
||||
self.blocks[-1].set_flash_processor(processor)
|
||||
|
||||
def query_geometry(
|
||||
self,
|
||||
model_fn: callable,
|
||||
queries: torch.Tensor,
|
||||
sample: torch.Tensor,
|
||||
grad: bool = False,
|
||||
):
|
||||
logits = model_fn(queries, sample)
|
||||
if grad:
|
||||
with torch.autocast(device_type="cuda", dtype=torch.float32):
|
||||
if self.grad_type == "numerical":
|
||||
interval = self.grad_interval
|
||||
grad_value = []
|
||||
for offset in [
|
||||
(interval, 0, 0),
|
||||
(0, interval, 0),
|
||||
(0, 0, interval),
|
||||
]:
|
||||
offset_tensor = torch.tensor(offset, device=queries.device)[
|
||||
None, :
|
||||
]
|
||||
res_p = model_fn(queries + offset_tensor, sample)[..., 0]
|
||||
res_n = model_fn(queries - offset_tensor, sample)[..., 0]
|
||||
grad_value.append((res_p - res_n) / (2 * interval))
|
||||
grad_value = torch.stack(grad_value, dim=-1)
|
||||
else:
|
||||
queries_d = torch.clone(queries)
|
||||
queries_d.requires_grad = True
|
||||
with torch.enable_grad():
|
||||
res_d = model_fn(queries_d, sample)
|
||||
grad_value = torch.autograd.grad(
|
||||
res_d,
|
||||
[queries_d],
|
||||
grad_outputs=torch.ones_like(res_d),
|
||||
create_graph=self.training,
|
||||
)[0]
|
||||
else:
|
||||
grad_value = None
|
||||
|
||||
return logits, grad_value
|
||||
|
||||
def forward(
|
||||
self,
|
||||
sample: torch.Tensor,
|
||||
queries: torch.Tensor,
|
||||
kv_cache: Optional[torch.Tensor] = None,
|
||||
):
|
||||
if kv_cache is None:
|
||||
hidden_states = sample
|
||||
for _, block in enumerate(self.blocks[:-1]):
|
||||
hidden_states = block(hidden_states)
|
||||
kv_cache = hidden_states
|
||||
|
||||
# query grid logits by cross attention
|
||||
def query_fn(q, kv):
|
||||
q = self.proj_query(q)
|
||||
l = self.blocks[-1](q, encoder_hidden_states=kv)
|
||||
return self.proj_out(self.norm_out(l))
|
||||
|
||||
logits, grad = self.query_geometry(
|
||||
query_fn, queries, kv_cache, grad=self.training
|
||||
)
|
||||
logits = logits * -1 if not isinstance(logits, Tuple) else logits[0] * -1
|
||||
|
||||
return logits, kv_cache
|
||||
|
||||
|
||||
class TripoSGVAEModel(ModelMixin, ConfigMixin):
|
||||
@register_to_config
|
||||
def __init__(
|
||||
self,
|
||||
in_channels: int = 3, # NOTE xyz instead of feature dim
|
||||
latent_channels: int = 64,
|
||||
num_attention_heads: int = 8,
|
||||
width_encoder: int = 512,
|
||||
width_decoder: int = 1024,
|
||||
num_layers_encoder: int = 8,
|
||||
num_layers_decoder: int = 16,
|
||||
embedding_type: str = "frequency",
|
||||
embed_frequency: int = 8,
|
||||
embed_include_pi: bool = False,
|
||||
):
|
||||
super().__init__()
|
||||
|
||||
self.out_channels = 1
|
||||
|
||||
if embedding_type == "frequency":
|
||||
self.embedder = FrequencyPositionalEmbedding(
|
||||
num_freqs=embed_frequency,
|
||||
logspace=True,
|
||||
input_dim=in_channels,
|
||||
include_pi=embed_include_pi,
|
||||
)
|
||||
else:
|
||||
raise NotImplementedError(
|
||||
f"Embedding type {embedding_type} is not supported."
|
||||
)
|
||||
|
||||
self.encoder = TripoSGEncoder(
|
||||
in_channels=in_channels + self.embedder.out_dim,
|
||||
dim=width_encoder,
|
||||
num_attention_heads=num_attention_heads,
|
||||
num_layers=num_layers_encoder,
|
||||
)
|
||||
self.decoder = TripoSGDecoder(
|
||||
in_channels=self.embedder.out_dim,
|
||||
out_channels=self.out_channels,
|
||||
dim=width_decoder,
|
||||
num_attention_heads=num_attention_heads,
|
||||
num_layers=num_layers_decoder,
|
||||
)
|
||||
|
||||
self.quant = nn.Linear(width_encoder, latent_channels * 2, bias=True)
|
||||
self.post_quant = nn.Linear(latent_channels, width_decoder, bias=True)
|
||||
|
||||
self.use_slicing = False
|
||||
self.slicing_length = 1
|
||||
|
||||
# Auto-select sampling method based on torch_cluster availability
|
||||
if TORCH_CLUSTER_AVAILABLE:
|
||||
self.sampling_version = 1 # Original method with torch_cluster
|
||||
print("Using sampling version 1 (torch_cluster)")
|
||||
else:
|
||||
self.sampling_version = 2 # Fixed method with pytorch3d
|
||||
print("Using sampling version 2 (pytorch3d) - torch_cluster not available")
|
||||
|
||||
def set_flash_decoder(self):
|
||||
self.decoder.set_flash_processor(FlashTripo2AttnProcessor2_0())
|
||||
|
||||
# Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.fuse_qkv_projections with FusedAttnProcessor2_0->FusedTripoSGAttnProcessor2_0
|
||||
def fuse_qkv_projections(self):
|
||||
"""
|
||||
Enables fused QKV projections. For self-attention modules, all projection matrices (i.e., query, key, value)
|
||||
are fused. For cross-attention modules, key and value projection matrices are fused.
|
||||
|
||||
<Tip warning={true}>
|
||||
|
||||
This API is 🧪 experimental.
|
||||
|
||||
</Tip>
|
||||
"""
|
||||
self.original_attn_processors = None
|
||||
|
||||
for _, attn_processor in self.attn_processors.items():
|
||||
if "Added" in str(attn_processor.__class__.__name__):
|
||||
raise ValueError(
|
||||
"`fuse_qkv_projections()` is not supported for models having added KV projections."
|
||||
)
|
||||
|
||||
self.original_attn_processors = self.attn_processors
|
||||
|
||||
for module in self.modules():
|
||||
if isinstance(module, Attention):
|
||||
module.fuse_projections(fuse=True)
|
||||
|
||||
self.set_attn_processor(FusedTripoSGAttnProcessor2_0())
|
||||
|
||||
# Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.unfuse_qkv_projections
|
||||
def unfuse_qkv_projections(self):
|
||||
"""Disables the fused QKV projection if enabled.
|
||||
|
||||
<Tip warning={true}>
|
||||
|
||||
This API is 🧪 experimental.
|
||||
|
||||
</Tip>
|
||||
|
||||
"""
|
||||
if self.original_attn_processors is not None:
|
||||
self.set_attn_processor(self.original_attn_processors)
|
||||
|
||||
@property
|
||||
# Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.attn_processors
|
||||
def attn_processors(self) -> Dict[str, AttentionProcessor]:
|
||||
r"""
|
||||
Returns:
|
||||
`dict` of attention processors: A dictionary containing all attention processors used in the model with
|
||||
indexed by its weight name.
|
||||
"""
|
||||
# set recursively
|
||||
processors = {}
|
||||
|
||||
def fn_recursive_add_processors(
|
||||
name: str,
|
||||
module: torch.nn.Module,
|
||||
processors: Dict[str, AttentionProcessor],
|
||||
):
|
||||
if hasattr(module, "get_processor"):
|
||||
processors[f"{name}.processor"] = module.get_processor()
|
||||
|
||||
for sub_name, child in module.named_children():
|
||||
fn_recursive_add_processors(f"{name}.{sub_name}", child, processors)
|
||||
|
||||
return processors
|
||||
|
||||
for name, module in self.named_children():
|
||||
fn_recursive_add_processors(name, module, processors)
|
||||
|
||||
return processors
|
||||
|
||||
# Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.set_attn_processor
|
||||
def set_attn_processor(
|
||||
self, processor: Union[AttentionProcessor, Dict[str, AttentionProcessor]]
|
||||
):
|
||||
r"""
|
||||
Sets the attention processor to use to compute attention.
|
||||
|
||||
Parameters:
|
||||
processor (`dict` of `AttentionProcessor` or only `AttentionProcessor`):
|
||||
The instantiated processor class or a dictionary of processor classes that will be set as the processor
|
||||
for **all** `Attention` layers.
|
||||
|
||||
If `processor` is a dict, the key needs to define the path to the corresponding cross attention
|
||||
processor. This is strongly recommended when setting trainable attention processors.
|
||||
|
||||
"""
|
||||
count = len(self.attn_processors.keys())
|
||||
|
||||
if isinstance(processor, dict) and len(processor) != count:
|
||||
raise ValueError(
|
||||
f"A dict of processors was passed, but the number of processors {len(processor)} does not match the"
|
||||
f" number of attention layers: {count}. Please make sure to pass {count} processor classes."
|
||||
)
|
||||
|
||||
def fn_recursive_attn_processor(name: str, module: torch.nn.Module, processor):
|
||||
if hasattr(module, "set_processor"):
|
||||
if not isinstance(processor, dict):
|
||||
module.set_processor(processor)
|
||||
else:
|
||||
module.set_processor(processor.pop(f"{name}.processor"))
|
||||
|
||||
for sub_name, child in module.named_children():
|
||||
fn_recursive_attn_processor(f"{name}.{sub_name}", child, processor)
|
||||
|
||||
for name, module in self.named_children():
|
||||
fn_recursive_attn_processor(name, module, processor)
|
||||
|
||||
def set_default_attn_processor(self):
|
||||
"""
|
||||
Disables custom attention processors and sets the default attention implementation.
|
||||
"""
|
||||
self.set_attn_processor(TripoSGAttnProcessor2_0())
|
||||
|
||||
def enable_slicing(self, slicing_length: int = 1) -> None:
|
||||
r"""
|
||||
Enable sliced VAE decoding. When this option is enabled, the VAE will split the input tensor in slices to
|
||||
compute decoding in several steps. This is useful to save some memory and allow larger batch sizes.
|
||||
"""
|
||||
self.use_slicing = True
|
||||
self.slicing_length = slicing_length
|
||||
|
||||
def disable_slicing(self) -> None:
|
||||
r"""
|
||||
Disable sliced VAE decoding. If `enable_slicing` was previously enabled, this method will go back to computing
|
||||
decoding in one step.
|
||||
"""
|
||||
self.use_slicing = False
|
||||
|
||||
def _sample_features(
|
||||
self, x: torch.Tensor, num_tokens: int = 2048, seed: Optional[int] = None
|
||||
):
|
||||
"""
|
||||
Sample points from features of the input point cloud.
|
||||
|
||||
Args:
|
||||
x (torch.Tensor): The input point cloud. shape: (B, N, C)
|
||||
num_tokens (int, optional): The number of points to sample. Defaults to 2048.
|
||||
seed (Optional[int], optional): The random seed. Defaults to None.
|
||||
"""
|
||||
rng = np.random.default_rng(seed)
|
||||
indices = rng.choice(
|
||||
x.shape[1], num_tokens * 4, replace=num_tokens * 4 > x.shape[1]
|
||||
)
|
||||
selected_points = x[:, indices]
|
||||
|
||||
batch_size, num_points, num_channels = selected_points.shape
|
||||
flattened_points = selected_points.view(batch_size * num_points, num_channels)
|
||||
batch_indices = (
|
||||
torch.arange(batch_size).to(x.device).repeat_interleave(num_points)
|
||||
)
|
||||
|
||||
# fps sampling
|
||||
sampling_ratio = 1.0 / 4
|
||||
|
||||
if not TORCH_CLUSTER_AVAILABLE:
|
||||
raise RuntimeError("torch_cluster not available but trying to use original sampling method")
|
||||
|
||||
sampled_indices = fps(
|
||||
flattened_points[:, :3],
|
||||
batch_indices,
|
||||
ratio=sampling_ratio,
|
||||
random_start=self.training,
|
||||
)
|
||||
sampled_points = flattened_points[sampled_indices].view(
|
||||
batch_size, -1, num_channels
|
||||
)
|
||||
|
||||
return sampled_points
|
||||
|
||||
def _sample_features2(
|
||||
self, x: torch.Tensor, num_tokens: int = 2048, seed: Optional[int] = None
|
||||
):
|
||||
"""
|
||||
Sample points from features of the input point cloud.
|
||||
FIXED VERSION: Per-batch FPS sampling with proper normalization and no zero padding.
|
||||
|
||||
Args:
|
||||
x (torch.Tensor): The input point cloud. shape: (B, N, C)
|
||||
num_tokens (int, optional): The number of points to sample. Defaults to 2048.
|
||||
seed (Optional[int], optional): The random seed. Defaults to None.
|
||||
"""
|
||||
rng = np.random.default_rng(seed)
|
||||
indices = rng.choice(
|
||||
x.shape[1], num_tokens * 4, replace=num_tokens * 4 > x.shape[1]
|
||||
)
|
||||
selected_points = x[:, indices]
|
||||
|
||||
batch_size, num_points, num_channels = selected_points.shape
|
||||
sampling_ratio = 1.0 / 4
|
||||
target_points_per_batch = int(num_points * sampling_ratio)
|
||||
|
||||
# FIXED: Apply FPS per-batch with coordinate normalization
|
||||
sampled_batches = []
|
||||
|
||||
for b in range(batch_size):
|
||||
batch_points = selected_points[b] # (num_points, num_channels)
|
||||
batch_xyz = batch_points[:, :3] # (num_points, 3)
|
||||
|
||||
# FIXED: Normalize coordinates within each batch to [0,1] for fair FPS
|
||||
xyz_min = batch_xyz.min(dim=0, keepdim=True)[0]
|
||||
xyz_max = batch_xyz.max(dim=0, keepdim=True)[0]
|
||||
xyz_range = xyz_max - xyz_min
|
||||
# Avoid division by zero
|
||||
xyz_range = torch.where(xyz_range < 1e-6, torch.ones_like(xyz_range), xyz_range)
|
||||
normalized_xyz = (batch_xyz - xyz_min) / xyz_range
|
||||
|
||||
# Apply FPS on normalized coordinates
|
||||
normalized_xyz_batch = normalized_xyz.unsqueeze(0) # (1, num_points, 3)
|
||||
_, sampled_indices = sample_farthest_points(normalized_xyz_batch, K=target_points_per_batch)
|
||||
sampled_indices = sampled_indices.squeeze(0) # (target_points_per_batch,)
|
||||
|
||||
# Get original (unnormalized) sampled points with all features
|
||||
sampled_batch = batch_points[sampled_indices] # (target_points_per_batch, num_channels)
|
||||
sampled_batches.append(sampled_batch)
|
||||
|
||||
# FIXED: Stack without zero padding - all batches have same number of points
|
||||
sampled_points = torch.stack(sampled_batches, dim=0) # (batch_size, target_points_per_batch, num_channels)
|
||||
|
||||
return sampled_points
|
||||
|
||||
def set_sampling_version(self, version: int):
|
||||
"""Switch between sampling versions for debugging"""
|
||||
if version not in [1, 2]:
|
||||
raise ValueError("Version must be 1 (original) or 2 (fixed)")
|
||||
|
||||
# Check if version 1 is requested but torch_cluster is not available
|
||||
if version == 1 and not TORCH_CLUSTER_AVAILABLE:
|
||||
print("Warning: Cannot use version 1 - torch_cluster not available, using version 2")
|
||||
version = 2
|
||||
|
||||
self.sampling_version = version
|
||||
print(f"Switched to sampling version {version}")
|
||||
|
||||
def compare_sampling_versions(self, x: torch.Tensor, num_tokens: int = 2048, seed: Optional[int] = None):
|
||||
"""Compare both sampling versions side by side"""
|
||||
print("COMPARING SAMPLING VERSIONS:")
|
||||
print("="*60)
|
||||
|
||||
# Test version 1 (original) only if torch_cluster is available
|
||||
if TORCH_CLUSTER_AVAILABLE:
|
||||
print("Testing ORIGINAL version 1...")
|
||||
with torch.no_grad():
|
||||
sampled_v1 = self._sample_features(x, num_tokens, seed)
|
||||
else:
|
||||
print("Skipping version 1 - torch_cluster not available")
|
||||
sampled_v1 = None
|
||||
|
||||
# Test version 2 (fixed)
|
||||
print("Testing FIXED version 2...")
|
||||
with torch.no_grad():
|
||||
sampled_v2 = self._sample_features2(x, num_tokens, seed)
|
||||
|
||||
print(f"\nRESULTS COMPARISON:")
|
||||
if sampled_v1 is not None:
|
||||
print(f" V1 shape: {sampled_v1.shape}")
|
||||
print(f" V2 shape: {sampled_v2.shape}")
|
||||
|
||||
# Check for zero padding
|
||||
versions_to_check = [(2, sampled_v2)]
|
||||
if sampled_v1 is not None:
|
||||
versions_to_check.insert(0, (1, sampled_v1))
|
||||
|
||||
for version, sampled in versions_to_check:
|
||||
print(f"\n Version {version} - Zero padding analysis:")
|
||||
for b in range(sampled.shape[0]):
|
||||
real_points = (sampled[b].abs().sum(-1) > 1e-6).sum().item()
|
||||
total_points = sampled[b].shape[0]
|
||||
zero_points = total_points - real_points
|
||||
print(f" Batch {b}: {real_points}/{total_points} real points ({zero_points} zeros)")
|
||||
|
||||
# Coordinate range comparison
|
||||
print(f"\n Coordinate ranges:")
|
||||
for version, sampled in versions_to_check:
|
||||
xyz = sampled[:, :, :3]
|
||||
real_mask = xyz.abs().sum(-1) > 1e-6
|
||||
if real_mask.any():
|
||||
real_xyz = xyz[real_mask]
|
||||
print(f" V{version}: [{real_xyz.min():.3f}, {real_xyz.max():.3f}] range={real_xyz.max()-real_xyz.min():.3f}")
|
||||
|
||||
print("="*60)
|
||||
return sampled_v1, sampled_v2
|
||||
|
||||
def _encode(
|
||||
self, x: torch.Tensor, num_tokens: int = 2048, seed: Optional[int] = None
|
||||
):
|
||||
position_channels = self.config.in_channels
|
||||
positions, features = x[..., :position_channels], x[..., position_channels:]
|
||||
x_kv = torch.cat([self.embedder(positions), features], dim=-1)
|
||||
|
||||
# Switch between sampling versions
|
||||
if self.sampling_version == 2:
|
||||
print(f"Using FIXED sampling version 2")
|
||||
sampled_x = self._sample_features2(x, num_tokens, seed)
|
||||
else:
|
||||
print(f"Using ORIGINAL sampling version 1")
|
||||
sampled_x = self._sample_features(x, num_tokens, seed)
|
||||
|
||||
positions, features = (
|
||||
sampled_x[..., :position_channels],
|
||||
sampled_x[..., position_channels:],
|
||||
)
|
||||
x_q = torch.cat([self.embedder(positions), features], dim=-1)
|
||||
|
||||
x = self.encoder(x_q, x_kv)
|
||||
|
||||
x = self.quant(x)
|
||||
|
||||
return x
|
||||
|
||||
@apply_forward_hook
|
||||
def encode(
|
||||
self, x: torch.Tensor, return_dict: bool = True, **kwargs
|
||||
) -> Union[AutoencoderKLOutput, Tuple[DiagonalGaussianDistribution]]:
|
||||
"""
|
||||
Encode a batch of point features into latents.
|
||||
"""
|
||||
if self.use_slicing and x.shape[0] > 1:
|
||||
encoded_slices = [
|
||||
self._encode(x_slice, **kwargs)
|
||||
for x_slice in x.split(self.slicing_length)
|
||||
]
|
||||
h = torch.cat(encoded_slices)
|
||||
else:
|
||||
h = self._encode(x, **kwargs)
|
||||
|
||||
posterior = DiagonalGaussianDistribution(h, feature_dim=-1)
|
||||
|
||||
if not return_dict:
|
||||
return (posterior,)
|
||||
return AutoencoderKLOutput(latent_dist=posterior)
|
||||
|
||||
def _decode(
|
||||
self,
|
||||
z: torch.Tensor,
|
||||
sampled_points: torch.Tensor,
|
||||
num_chunks: int = 50000,
|
||||
to_cpu: bool = False,
|
||||
return_dict: bool = True,
|
||||
) -> Union[DecoderOutput, torch.Tensor]:
|
||||
xyz_samples = sampled_points
|
||||
|
||||
z = self.post_quant(z)
|
||||
|
||||
num_points = xyz_samples.shape[1]
|
||||
kv_cache = None
|
||||
dec = []
|
||||
|
||||
for i in range(0, num_points, num_chunks):
|
||||
queries = xyz_samples[:, i : i + num_chunks, :].to(z.device, dtype=z.dtype)
|
||||
queries = self.embedder(queries)
|
||||
|
||||
z_, kv_cache = self.decoder(z, queries, kv_cache)
|
||||
dec.append(z_ if not to_cpu else z_.cpu())
|
||||
|
||||
z = torch.cat(dec, dim=1)
|
||||
|
||||
if not return_dict:
|
||||
return (z,)
|
||||
|
||||
return DecoderOutput(sample=z)
|
||||
|
||||
@apply_forward_hook
|
||||
def decode(
|
||||
self,
|
||||
z: torch.Tensor,
|
||||
sampled_points: torch.Tensor,
|
||||
return_dict: bool = True,
|
||||
**kwargs,
|
||||
) -> Union[DecoderOutput, torch.Tensor]:
|
||||
if self.use_slicing and z.shape[0] > 1:
|
||||
decoded_slices = [
|
||||
self._decode(z_slice, p_slice, **kwargs).sample
|
||||
for z_slice, p_slice in zip(
|
||||
z.split(self.slicing_length),
|
||||
sampled_points.split(self.slicing_length),
|
||||
)
|
||||
]
|
||||
decoded = torch.cat(decoded_slices)
|
||||
else:
|
||||
decoded = self._decode(z, sampled_points, **kwargs).sample
|
||||
|
||||
if not return_dict:
|
||||
return (decoded,)
|
||||
return DecoderOutput(sample=decoded)
|
||||
|
||||
def forward(self, x: torch.Tensor):
|
||||
pass
|
||||
@@ -0,0 +1,69 @@
|
||||
from typing import Optional, Tuple
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers.utils.torch_utils import randn_tensor
|
||||
|
||||
|
||||
class DiagonalGaussianDistribution(object):
|
||||
def __init__(
|
||||
self,
|
||||
parameters: torch.Tensor,
|
||||
deterministic: bool = False,
|
||||
feature_dim: int = 1,
|
||||
):
|
||||
self.parameters = parameters
|
||||
self.feature_dim = feature_dim
|
||||
self.mean, self.logvar = torch.chunk(parameters, 2, dim=feature_dim)
|
||||
self.logvar = torch.clamp(self.logvar, -30.0, 20.0)
|
||||
self.deterministic = deterministic
|
||||
self.std = torch.exp(0.5 * self.logvar)
|
||||
self.var = torch.exp(self.logvar)
|
||||
if self.deterministic:
|
||||
self.var = self.std = torch.zeros_like(
|
||||
self.mean, device=self.parameters.device, dtype=self.parameters.dtype
|
||||
)
|
||||
|
||||
def sample(self, generator: Optional[torch.Generator] = None) -> torch.Tensor:
|
||||
# make sure sample is on the same device as the parameters and has same dtype
|
||||
sample = randn_tensor(
|
||||
self.mean.shape,
|
||||
generator=generator,
|
||||
device=self.parameters.device,
|
||||
dtype=self.parameters.dtype,
|
||||
)
|
||||
x = self.mean + self.std * sample
|
||||
return x
|
||||
|
||||
def kl(self, other: "DiagonalGaussianDistribution" = None) -> torch.Tensor:
|
||||
if self.deterministic:
|
||||
return torch.Tensor([0.0])
|
||||
else:
|
||||
if other is None:
|
||||
return 0.5 * torch.sum(
|
||||
torch.pow(self.mean, 2) + self.var - 1.0 - self.logvar,
|
||||
dim=[1, 2, 3],
|
||||
)
|
||||
else:
|
||||
return 0.5 * torch.sum(
|
||||
torch.pow(self.mean - other.mean, 2) / other.var
|
||||
+ self.var / other.var
|
||||
- 1.0
|
||||
- self.logvar
|
||||
+ other.logvar,
|
||||
dim=[1, 2, 3],
|
||||
)
|
||||
|
||||
def nll(
|
||||
self, sample: torch.Tensor, dims: Tuple[int, ...] = [1, 2, 3]
|
||||
) -> torch.Tensor:
|
||||
if self.deterministic:
|
||||
return torch.Tensor([0.0])
|
||||
logtwopi = np.log(2.0 * np.pi)
|
||||
return 0.5 * torch.sum(
|
||||
logtwopi + self.logvar + torch.pow(sample - self.mean, 2) / self.var,
|
||||
dim=dims,
|
||||
)
|
||||
|
||||
def mode(self) -> torch.Tensor:
|
||||
return self.mean
|
||||
@@ -0,0 +1,464 @@
|
||||
"""
|
||||
Source and Copyright Notice:
|
||||
This code is from briaai/RMBG-1.4
|
||||
Original repository: https://huggingface.co/briaai/RMBG-1.4
|
||||
Copyright belongs to briaai
|
||||
"""
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
from huggingface_hub import PyTorchModelHubMixin
|
||||
|
||||
class REBNCONV(nn.Module):
|
||||
def __init__(self,in_ch=3,out_ch=3,dirate=1,stride=1):
|
||||
super(REBNCONV,self).__init__()
|
||||
|
||||
self.conv_s1 = nn.Conv2d(in_ch,out_ch,3,padding=1*dirate,dilation=1*dirate,stride=stride)
|
||||
self.bn_s1 = nn.BatchNorm2d(out_ch)
|
||||
self.relu_s1 = nn.ReLU(inplace=True)
|
||||
|
||||
def forward(self,x):
|
||||
|
||||
hx = x
|
||||
xout = self.relu_s1(self.bn_s1(self.conv_s1(hx)))
|
||||
|
||||
return xout
|
||||
|
||||
## upsample tensor 'src' to have the same spatial size with tensor 'tar'
|
||||
def _upsample_like(src,tar):
|
||||
|
||||
src = F.interpolate(src,size=tar.shape[2:],mode='bilinear')
|
||||
|
||||
return src
|
||||
|
||||
|
||||
### RSU-7 ###
|
||||
class RSU7(nn.Module):
|
||||
|
||||
def __init__(self, in_ch=3, mid_ch=12, out_ch=3, img_size=512):
|
||||
super(RSU7,self).__init__()
|
||||
|
||||
self.in_ch = in_ch
|
||||
self.mid_ch = mid_ch
|
||||
self.out_ch = out_ch
|
||||
|
||||
self.rebnconvin = REBNCONV(in_ch,out_ch,dirate=1) ## 1 -> 1/2
|
||||
|
||||
self.rebnconv1 = REBNCONV(out_ch,mid_ch,dirate=1)
|
||||
self.pool1 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.rebnconv2 = REBNCONV(mid_ch,mid_ch,dirate=1)
|
||||
self.pool2 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.rebnconv3 = REBNCONV(mid_ch,mid_ch,dirate=1)
|
||||
self.pool3 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.rebnconv4 = REBNCONV(mid_ch,mid_ch,dirate=1)
|
||||
self.pool4 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.rebnconv5 = REBNCONV(mid_ch,mid_ch,dirate=1)
|
||||
self.pool5 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.rebnconv6 = REBNCONV(mid_ch,mid_ch,dirate=1)
|
||||
|
||||
self.rebnconv7 = REBNCONV(mid_ch,mid_ch,dirate=2)
|
||||
|
||||
self.rebnconv6d = REBNCONV(mid_ch*2,mid_ch,dirate=1)
|
||||
self.rebnconv5d = REBNCONV(mid_ch*2,mid_ch,dirate=1)
|
||||
self.rebnconv4d = REBNCONV(mid_ch*2,mid_ch,dirate=1)
|
||||
self.rebnconv3d = REBNCONV(mid_ch*2,mid_ch,dirate=1)
|
||||
self.rebnconv2d = REBNCONV(mid_ch*2,mid_ch,dirate=1)
|
||||
self.rebnconv1d = REBNCONV(mid_ch*2,out_ch,dirate=1)
|
||||
|
||||
def forward(self,x):
|
||||
b, c, h, w = x.shape
|
||||
|
||||
hx = x
|
||||
hxin = self.rebnconvin(hx)
|
||||
|
||||
hx1 = self.rebnconv1(hxin)
|
||||
hx = self.pool1(hx1)
|
||||
|
||||
hx2 = self.rebnconv2(hx)
|
||||
hx = self.pool2(hx2)
|
||||
|
||||
hx3 = self.rebnconv3(hx)
|
||||
hx = self.pool3(hx3)
|
||||
|
||||
hx4 = self.rebnconv4(hx)
|
||||
hx = self.pool4(hx4)
|
||||
|
||||
hx5 = self.rebnconv5(hx)
|
||||
hx = self.pool5(hx5)
|
||||
|
||||
hx6 = self.rebnconv6(hx)
|
||||
|
||||
hx7 = self.rebnconv7(hx6)
|
||||
|
||||
hx6d = self.rebnconv6d(torch.cat((hx7,hx6),1))
|
||||
hx6dup = _upsample_like(hx6d,hx5)
|
||||
|
||||
hx5d = self.rebnconv5d(torch.cat((hx6dup,hx5),1))
|
||||
hx5dup = _upsample_like(hx5d,hx4)
|
||||
|
||||
hx4d = self.rebnconv4d(torch.cat((hx5dup,hx4),1))
|
||||
hx4dup = _upsample_like(hx4d,hx3)
|
||||
|
||||
hx3d = self.rebnconv3d(torch.cat((hx4dup,hx3),1))
|
||||
hx3dup = _upsample_like(hx3d,hx2)
|
||||
|
||||
hx2d = self.rebnconv2d(torch.cat((hx3dup,hx2),1))
|
||||
hx2dup = _upsample_like(hx2d,hx1)
|
||||
|
||||
hx1d = self.rebnconv1d(torch.cat((hx2dup,hx1),1))
|
||||
|
||||
return hx1d + hxin
|
||||
|
||||
|
||||
### RSU-6 ###
|
||||
class RSU6(nn.Module):
|
||||
|
||||
def __init__(self, in_ch=3, mid_ch=12, out_ch=3):
|
||||
super(RSU6,self).__init__()
|
||||
|
||||
self.rebnconvin = REBNCONV(in_ch,out_ch,dirate=1)
|
||||
|
||||
self.rebnconv1 = REBNCONV(out_ch,mid_ch,dirate=1)
|
||||
self.pool1 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.rebnconv2 = REBNCONV(mid_ch,mid_ch,dirate=1)
|
||||
self.pool2 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.rebnconv3 = REBNCONV(mid_ch,mid_ch,dirate=1)
|
||||
self.pool3 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.rebnconv4 = REBNCONV(mid_ch,mid_ch,dirate=1)
|
||||
self.pool4 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.rebnconv5 = REBNCONV(mid_ch,mid_ch,dirate=1)
|
||||
|
||||
self.rebnconv6 = REBNCONV(mid_ch,mid_ch,dirate=2)
|
||||
|
||||
self.rebnconv5d = REBNCONV(mid_ch*2,mid_ch,dirate=1)
|
||||
self.rebnconv4d = REBNCONV(mid_ch*2,mid_ch,dirate=1)
|
||||
self.rebnconv3d = REBNCONV(mid_ch*2,mid_ch,dirate=1)
|
||||
self.rebnconv2d = REBNCONV(mid_ch*2,mid_ch,dirate=1)
|
||||
self.rebnconv1d = REBNCONV(mid_ch*2,out_ch,dirate=1)
|
||||
|
||||
def forward(self,x):
|
||||
|
||||
hx = x
|
||||
|
||||
hxin = self.rebnconvin(hx)
|
||||
|
||||
hx1 = self.rebnconv1(hxin)
|
||||
hx = self.pool1(hx1)
|
||||
|
||||
hx2 = self.rebnconv2(hx)
|
||||
hx = self.pool2(hx2)
|
||||
|
||||
hx3 = self.rebnconv3(hx)
|
||||
hx = self.pool3(hx3)
|
||||
|
||||
hx4 = self.rebnconv4(hx)
|
||||
hx = self.pool4(hx4)
|
||||
|
||||
hx5 = self.rebnconv5(hx)
|
||||
|
||||
hx6 = self.rebnconv6(hx5)
|
||||
|
||||
|
||||
hx5d = self.rebnconv5d(torch.cat((hx6,hx5),1))
|
||||
hx5dup = _upsample_like(hx5d,hx4)
|
||||
|
||||
hx4d = self.rebnconv4d(torch.cat((hx5dup,hx4),1))
|
||||
hx4dup = _upsample_like(hx4d,hx3)
|
||||
|
||||
hx3d = self.rebnconv3d(torch.cat((hx4dup,hx3),1))
|
||||
hx3dup = _upsample_like(hx3d,hx2)
|
||||
|
||||
hx2d = self.rebnconv2d(torch.cat((hx3dup,hx2),1))
|
||||
hx2dup = _upsample_like(hx2d,hx1)
|
||||
|
||||
hx1d = self.rebnconv1d(torch.cat((hx2dup,hx1),1))
|
||||
|
||||
return hx1d + hxin
|
||||
|
||||
### RSU-5 ###
|
||||
class RSU5(nn.Module):
|
||||
|
||||
def __init__(self, in_ch=3, mid_ch=12, out_ch=3):
|
||||
super(RSU5,self).__init__()
|
||||
|
||||
self.rebnconvin = REBNCONV(in_ch,out_ch,dirate=1)
|
||||
|
||||
self.rebnconv1 = REBNCONV(out_ch,mid_ch,dirate=1)
|
||||
self.pool1 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.rebnconv2 = REBNCONV(mid_ch,mid_ch,dirate=1)
|
||||
self.pool2 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.rebnconv3 = REBNCONV(mid_ch,mid_ch,dirate=1)
|
||||
self.pool3 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.rebnconv4 = REBNCONV(mid_ch,mid_ch,dirate=1)
|
||||
|
||||
self.rebnconv5 = REBNCONV(mid_ch,mid_ch,dirate=2)
|
||||
|
||||
self.rebnconv4d = REBNCONV(mid_ch*2,mid_ch,dirate=1)
|
||||
self.rebnconv3d = REBNCONV(mid_ch*2,mid_ch,dirate=1)
|
||||
self.rebnconv2d = REBNCONV(mid_ch*2,mid_ch,dirate=1)
|
||||
self.rebnconv1d = REBNCONV(mid_ch*2,out_ch,dirate=1)
|
||||
|
||||
def forward(self,x):
|
||||
|
||||
hx = x
|
||||
|
||||
hxin = self.rebnconvin(hx)
|
||||
|
||||
hx1 = self.rebnconv1(hxin)
|
||||
hx = self.pool1(hx1)
|
||||
|
||||
hx2 = self.rebnconv2(hx)
|
||||
hx = self.pool2(hx2)
|
||||
|
||||
hx3 = self.rebnconv3(hx)
|
||||
hx = self.pool3(hx3)
|
||||
|
||||
hx4 = self.rebnconv4(hx)
|
||||
|
||||
hx5 = self.rebnconv5(hx4)
|
||||
|
||||
hx4d = self.rebnconv4d(torch.cat((hx5,hx4),1))
|
||||
hx4dup = _upsample_like(hx4d,hx3)
|
||||
|
||||
hx3d = self.rebnconv3d(torch.cat((hx4dup,hx3),1))
|
||||
hx3dup = _upsample_like(hx3d,hx2)
|
||||
|
||||
hx2d = self.rebnconv2d(torch.cat((hx3dup,hx2),1))
|
||||
hx2dup = _upsample_like(hx2d,hx1)
|
||||
|
||||
hx1d = self.rebnconv1d(torch.cat((hx2dup,hx1),1))
|
||||
|
||||
return hx1d + hxin
|
||||
|
||||
### RSU-4 ###
|
||||
class RSU4(nn.Module):
|
||||
|
||||
def __init__(self, in_ch=3, mid_ch=12, out_ch=3):
|
||||
super(RSU4,self).__init__()
|
||||
|
||||
self.rebnconvin = REBNCONV(in_ch,out_ch,dirate=1)
|
||||
|
||||
self.rebnconv1 = REBNCONV(out_ch,mid_ch,dirate=1)
|
||||
self.pool1 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.rebnconv2 = REBNCONV(mid_ch,mid_ch,dirate=1)
|
||||
self.pool2 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.rebnconv3 = REBNCONV(mid_ch,mid_ch,dirate=1)
|
||||
|
||||
self.rebnconv4 = REBNCONV(mid_ch,mid_ch,dirate=2)
|
||||
|
||||
self.rebnconv3d = REBNCONV(mid_ch*2,mid_ch,dirate=1)
|
||||
self.rebnconv2d = REBNCONV(mid_ch*2,mid_ch,dirate=1)
|
||||
self.rebnconv1d = REBNCONV(mid_ch*2,out_ch,dirate=1)
|
||||
|
||||
def forward(self,x):
|
||||
|
||||
hx = x
|
||||
|
||||
hxin = self.rebnconvin(hx)
|
||||
|
||||
hx1 = self.rebnconv1(hxin)
|
||||
hx = self.pool1(hx1)
|
||||
|
||||
hx2 = self.rebnconv2(hx)
|
||||
hx = self.pool2(hx2)
|
||||
|
||||
hx3 = self.rebnconv3(hx)
|
||||
|
||||
hx4 = self.rebnconv4(hx3)
|
||||
|
||||
hx3d = self.rebnconv3d(torch.cat((hx4,hx3),1))
|
||||
hx3dup = _upsample_like(hx3d,hx2)
|
||||
|
||||
hx2d = self.rebnconv2d(torch.cat((hx3dup,hx2),1))
|
||||
hx2dup = _upsample_like(hx2d,hx1)
|
||||
|
||||
hx1d = self.rebnconv1d(torch.cat((hx2dup,hx1),1))
|
||||
|
||||
return hx1d + hxin
|
||||
|
||||
### RSU-4F ###
|
||||
class RSU4F(nn.Module):
|
||||
|
||||
def __init__(self, in_ch=3, mid_ch=12, out_ch=3):
|
||||
super(RSU4F,self).__init__()
|
||||
|
||||
self.rebnconvin = REBNCONV(in_ch,out_ch,dirate=1)
|
||||
|
||||
self.rebnconv1 = REBNCONV(out_ch,mid_ch,dirate=1)
|
||||
self.rebnconv2 = REBNCONV(mid_ch,mid_ch,dirate=2)
|
||||
self.rebnconv3 = REBNCONV(mid_ch,mid_ch,dirate=4)
|
||||
|
||||
self.rebnconv4 = REBNCONV(mid_ch,mid_ch,dirate=8)
|
||||
|
||||
self.rebnconv3d = REBNCONV(mid_ch*2,mid_ch,dirate=4)
|
||||
self.rebnconv2d = REBNCONV(mid_ch*2,mid_ch,dirate=2)
|
||||
self.rebnconv1d = REBNCONV(mid_ch*2,out_ch,dirate=1)
|
||||
|
||||
def forward(self,x):
|
||||
|
||||
hx = x
|
||||
|
||||
hxin = self.rebnconvin(hx)
|
||||
|
||||
hx1 = self.rebnconv1(hxin)
|
||||
hx2 = self.rebnconv2(hx1)
|
||||
hx3 = self.rebnconv3(hx2)
|
||||
|
||||
hx4 = self.rebnconv4(hx3)
|
||||
|
||||
hx3d = self.rebnconv3d(torch.cat((hx4,hx3),1))
|
||||
hx2d = self.rebnconv2d(torch.cat((hx3d,hx2),1))
|
||||
hx1d = self.rebnconv1d(torch.cat((hx2d,hx1),1))
|
||||
|
||||
return hx1d + hxin
|
||||
|
||||
|
||||
class myrebnconv(nn.Module):
|
||||
def __init__(self, in_ch=3,
|
||||
out_ch=1,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1,
|
||||
dilation=1,
|
||||
groups=1):
|
||||
super(myrebnconv,self).__init__()
|
||||
|
||||
self.conv = nn.Conv2d(in_ch,
|
||||
out_ch,
|
||||
kernel_size=kernel_size,
|
||||
stride=stride,
|
||||
padding=padding,
|
||||
dilation=dilation,
|
||||
groups=groups)
|
||||
self.bn = nn.BatchNorm2d(out_ch)
|
||||
self.rl = nn.ReLU(inplace=True)
|
||||
|
||||
def forward(self,x):
|
||||
return self.rl(self.bn(self.conv(x)))
|
||||
|
||||
|
||||
class BriaRMBG(nn.Module, PyTorchModelHubMixin):
|
||||
|
||||
def __init__(self,config:dict={"in_ch":3,"out_ch":1}):
|
||||
super(BriaRMBG,self).__init__()
|
||||
in_ch=config["in_ch"]
|
||||
out_ch=config["out_ch"]
|
||||
self.conv_in = nn.Conv2d(in_ch,64,3,stride=2,padding=1)
|
||||
self.pool_in = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.stage1 = RSU7(64,32,64)
|
||||
self.pool12 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.stage2 = RSU6(64,32,128)
|
||||
self.pool23 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.stage3 = RSU5(128,64,256)
|
||||
self.pool34 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.stage4 = RSU4(256,128,512)
|
||||
self.pool45 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.stage5 = RSU4F(512,256,512)
|
||||
self.pool56 = nn.MaxPool2d(2,stride=2,ceil_mode=True)
|
||||
|
||||
self.stage6 = RSU4F(512,256,512)
|
||||
|
||||
# decoder
|
||||
self.stage5d = RSU4F(1024,256,512)
|
||||
self.stage4d = RSU4(1024,128,256)
|
||||
self.stage3d = RSU5(512,64,128)
|
||||
self.stage2d = RSU6(256,32,64)
|
||||
self.stage1d = RSU7(128,16,64)
|
||||
|
||||
self.side1 = nn.Conv2d(64,out_ch,3,padding=1)
|
||||
self.side2 = nn.Conv2d(64,out_ch,3,padding=1)
|
||||
self.side3 = nn.Conv2d(128,out_ch,3,padding=1)
|
||||
self.side4 = nn.Conv2d(256,out_ch,3,padding=1)
|
||||
self.side5 = nn.Conv2d(512,out_ch,3,padding=1)
|
||||
self.side6 = nn.Conv2d(512,out_ch,3,padding=1)
|
||||
|
||||
# self.outconv = nn.Conv2d(6*out_ch,out_ch,1)
|
||||
|
||||
def forward(self,x):
|
||||
|
||||
hx = x
|
||||
|
||||
hxin = self.conv_in(hx)
|
||||
#hx = self.pool_in(hxin)
|
||||
|
||||
#stage 1
|
||||
hx1 = self.stage1(hxin)
|
||||
hx = self.pool12(hx1)
|
||||
|
||||
#stage 2
|
||||
hx2 = self.stage2(hx)
|
||||
hx = self.pool23(hx2)
|
||||
|
||||
#stage 3
|
||||
hx3 = self.stage3(hx)
|
||||
hx = self.pool34(hx3)
|
||||
|
||||
#stage 4
|
||||
hx4 = self.stage4(hx)
|
||||
hx = self.pool45(hx4)
|
||||
|
||||
#stage 5
|
||||
hx5 = self.stage5(hx)
|
||||
hx = self.pool56(hx5)
|
||||
|
||||
#stage 6
|
||||
hx6 = self.stage6(hx)
|
||||
hx6up = _upsample_like(hx6,hx5)
|
||||
|
||||
#-------------------- decoder --------------------
|
||||
hx5d = self.stage5d(torch.cat((hx6up,hx5),1))
|
||||
hx5dup = _upsample_like(hx5d,hx4)
|
||||
|
||||
hx4d = self.stage4d(torch.cat((hx5dup,hx4),1))
|
||||
hx4dup = _upsample_like(hx4d,hx3)
|
||||
|
||||
hx3d = self.stage3d(torch.cat((hx4dup,hx3),1))
|
||||
hx3dup = _upsample_like(hx3d,hx2)
|
||||
|
||||
hx2d = self.stage2d(torch.cat((hx3dup,hx2),1))
|
||||
hx2dup = _upsample_like(hx2d,hx1)
|
||||
|
||||
hx1d = self.stage1d(torch.cat((hx2dup,hx1),1))
|
||||
|
||||
|
||||
#side output
|
||||
d1 = self.side1(hx1d)
|
||||
d1 = _upsample_like(d1,x)
|
||||
|
||||
d2 = self.side2(hx2d)
|
||||
d2 = _upsample_like(d2,x)
|
||||
|
||||
d3 = self.side3(hx3d)
|
||||
d3 = _upsample_like(d3,x)
|
||||
|
||||
d4 = self.side4(hx4d)
|
||||
d4 = _upsample_like(d4,x)
|
||||
|
||||
d5 = self.side5(hx5d)
|
||||
d5 = _upsample_like(d5,x)
|
||||
|
||||
d6 = self.side6(hx6)
|
||||
d6 = _upsample_like(d6,x)
|
||||
|
||||
return [F.sigmoid(d1), F.sigmoid(d2), F.sigmoid(d3), F.sigmoid(d4), F.sigmoid(d5), F.sigmoid(d6)],[hx1d,hx2d,hx3d,hx4d,hx5d,hx6]
|
||||
|
||||
@@ -0,0 +1,96 @@
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
|
||||
|
||||
class FrequencyPositionalEmbedding(nn.Module):
|
||||
"""The sin/cosine positional embedding. Given an input tensor `x` of shape [n_batch, ..., c_dim], it converts
|
||||
each feature dimension of `x[..., i]` into:
|
||||
[
|
||||
sin(x[..., i]),
|
||||
sin(f_1*x[..., i]),
|
||||
sin(f_2*x[..., i]),
|
||||
...
|
||||
sin(f_N * x[..., i]),
|
||||
cos(x[..., i]),
|
||||
cos(f_1*x[..., i]),
|
||||
cos(f_2*x[..., i]),
|
||||
...
|
||||
cos(f_N * x[..., i]),
|
||||
x[..., i] # only present if include_input is True.
|
||||
], here f_i is the frequency.
|
||||
|
||||
Denote the space is [0 / num_freqs, 1 / num_freqs, 2 / num_freqs, 3 / num_freqs, ..., (num_freqs - 1) / num_freqs].
|
||||
If logspace is True, then the frequency f_i is [2^(0 / num_freqs), ..., 2^(i / num_freqs), ...];
|
||||
Otherwise, the frequencies are linearly spaced between [1.0, 2^(num_freqs - 1)].
|
||||
|
||||
Args:
|
||||
num_freqs (int): the number of frequencies, default is 6;
|
||||
logspace (bool): If logspace is True, then the frequency f_i is [..., 2^(i / num_freqs), ...],
|
||||
otherwise, the frequencies are linearly spaced between [1.0, 2^(num_freqs - 1)];
|
||||
input_dim (int): the input dimension, default is 3;
|
||||
include_input (bool): include the input tensor or not, default is True.
|
||||
|
||||
Attributes:
|
||||
frequencies (torch.Tensor): If logspace is True, then the frequency f_i is [..., 2^(i / num_freqs), ...],
|
||||
otherwise, the frequencies are linearly spaced between [1.0, 2^(num_freqs - 1);
|
||||
|
||||
out_dim (int): the embedding size, if include_input is True, it is input_dim * (num_freqs * 2 + 1),
|
||||
otherwise, it is input_dim * num_freqs * 2.
|
||||
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
num_freqs: int = 6,
|
||||
logspace: bool = True,
|
||||
input_dim: int = 3,
|
||||
include_input: bool = True,
|
||||
include_pi: bool = True,
|
||||
) -> None:
|
||||
"""The initialization"""
|
||||
|
||||
super().__init__()
|
||||
|
||||
if logspace:
|
||||
frequencies = 2.0 ** torch.arange(num_freqs, dtype=torch.float32)
|
||||
else:
|
||||
frequencies = torch.linspace(
|
||||
1.0, 2.0 ** (num_freqs - 1), num_freqs, dtype=torch.float32
|
||||
)
|
||||
|
||||
if include_pi:
|
||||
frequencies *= torch.pi
|
||||
|
||||
self.register_buffer("frequencies", frequencies, persistent=False)
|
||||
self.include_input = include_input
|
||||
self.num_freqs = num_freqs
|
||||
|
||||
self.out_dim = self.get_dims(input_dim)
|
||||
|
||||
def get_dims(self, input_dim):
|
||||
temp = 1 if self.include_input or self.num_freqs == 0 else 0
|
||||
out_dim = input_dim * (self.num_freqs * 2 + temp)
|
||||
|
||||
return out_dim
|
||||
|
||||
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
||||
"""Forward process.
|
||||
|
||||
Args:
|
||||
x: tensor of shape [..., dim]
|
||||
|
||||
Returns:
|
||||
embedding: an embedding of `x` of shape [..., dim * (num_freqs * 2 + temp)]
|
||||
where temp is 1 if include_input is True and 0 otherwise.
|
||||
"""
|
||||
|
||||
if self.num_freqs > 0:
|
||||
embed = (x[..., None].contiguous() * self.frequencies).view(
|
||||
*x.shape[:-1], -1
|
||||
)
|
||||
if self.include_input:
|
||||
return torch.cat((x, embed.sin(), embed.cos()), dim=-1)
|
||||
else:
|
||||
return torch.cat((embed.sin(), embed.cos()), dim=-1)
|
||||
else:
|
||||
return x
|
||||
@@ -0,0 +1,3 @@
|
||||
from typing import Callable, Optional
|
||||
|
||||
from .partcrafter_transformer import PartCrafterDiTModel
|
||||
+8
@@ -0,0 +1,8 @@
|
||||
from dataclasses import dataclass
|
||||
|
||||
import torch
|
||||
|
||||
|
||||
@dataclass
|
||||
class Transformer1DModelOutput:
|
||||
sample: torch.FloatTensor
|
||||
Executable
+813
@@ -0,0 +1,813 @@
|
||||
# Copyright (c) 2025 Yuchen Lin
|
||||
|
||||
# This code is based on TripoSG (https://github.com/VAST-AI-Research/TripoSG). Below is the statement from the original repository:
|
||||
|
||||
# This code is based on Tencent HunyuanDiT (https://huggingface.co/Tencent-Hunyuan/HunyuanDiT),
|
||||
# which is licensed under the Tencent Hunyuan Community License Agreement.
|
||||
# Portions of this code are copied or adapted from HunyuanDiT.
|
||||
# See the original license below:
|
||||
|
||||
# ---- Start of Tencent Hunyuan Community License Agreement ----
|
||||
|
||||
# TENCENT HUNYUAN COMMUNITY LICENSE AGREEMENT
|
||||
# Tencent Hunyuan DiT Release Date: 14 May 2024
|
||||
# THIS LICENSE AGREEMENT DOES NOT APPLY IN THE EUROPEAN UNION AND IS EXPRESSLY LIMITED TO THE TERRITORY, AS DEFINED BELOW.
|
||||
# By clicking to agree or by using, reproducing, modifying, distributing, performing or displaying any portion or element of the Tencent Hunyuan Works, including via any Hosted Service, You will be deemed to have recognized and accepted the content of this Agreement, which is effective immediately.
|
||||
# 1. DEFINITIONS.
|
||||
# a. “Acceptable Use Policy” shall mean the policy made available by Tencent as set forth in the Exhibit A.
|
||||
# b. “Agreement” shall mean the terms and conditions for use, reproduction, distribution, modification, performance and displaying of Tencent Hunyuan Works or any portion or element thereof set forth herein.
|
||||
# c. “Documentation” shall mean the specifications, manuals and documentation for Tencent Hunyuan made publicly available by Tencent.
|
||||
# d. “Hosted Service” shall mean a hosted service offered via an application programming interface (API), web access, or any other electronic or remote means.
|
||||
# e. “Licensee,” “You” or “Your” shall mean a natural person or legal entity exercising the rights granted by this Agreement and/or using the Tencent Hunyuan Works for any purpose and in any field of use.
|
||||
# f. “Materials” shall mean, collectively, Tencent’s proprietary Tencent Hunyuan and Documentation (and any portion thereof) as made available by Tencent under this Agreement.
|
||||
# g. “Model Derivatives” shall mean all: (i) modifications to Tencent Hunyuan or any Model Derivative of Tencent Hunyuan; (ii) works based on Tencent Hunyuan or any Model Derivative of Tencent Hunyuan; or (iii) any other machine learning model which is created by transfer of patterns of the weights, parameters, operations, or Output of Tencent Hunyuan or any Model Derivative of Tencent Hunyuan, to that model in order to cause that model to perform similarly to Tencent Hunyuan or a Model Derivative of Tencent Hunyuan, including distillation methods, methods that use intermediate data representations, or methods based on the generation of synthetic data Outputs by Tencent Hunyuan or a Model Derivative of Tencent Hunyuan for training that model. For clarity, Outputs by themselves are not deemed Model Derivatives.
|
||||
# h. “Output” shall mean the information and/or content output of Tencent Hunyuan or a Model Derivative that results from operating or otherwise using Tencent Hunyuan or a Model Derivative, including via a Hosted Service.
|
||||
# i. “Tencent,” “We” or “Us” shall mean THL A29 Limited.
|
||||
# j. “Tencent Hunyuan” shall mean the large language models, text/image/video/audio/3D generation models, and multimodal large language models and their software and algorithms, including trained model weights, parameters (including optimizer states), machine-learning model code, inference-enabling code, training-enabling code, fine-tuning enabling code and other elements of the foregoing made publicly available by Us, including, without limitation to, Tencent Hunyuan DiT released at https://huggingface.co/Tencent-Hunyuan/HunyuanDiT.
|
||||
# k. “Tencent Hunyuan Works” shall mean: (i) the Materials; (ii) Model Derivatives; and (iii) all derivative works thereof.
|
||||
# l. “Territory” shall mean the worldwide territory, excluding the territory of the European Union.
|
||||
# m. “Third Party” or “Third Parties” shall mean individuals or legal entities that are not under common control with Us or You.
|
||||
# n. “including” shall mean including but not limited to.
|
||||
# 2. GRANT OF RIGHTS.
|
||||
# We grant You, for the Territory only, a non-exclusive, non-transferable and royalty-free limited license under Tencent’s intellectual property or other rights owned by Us embodied in or utilized by the Materials to use, reproduce, distribute, create derivative works of (including Model Derivatives), and make modifications to the Materials, only in accordance with the terms of this Agreement and the Acceptable Use Policy, and You must not violate (or encourage or permit anyone else to violate) any term of this Agreement or the Acceptable Use Policy.
|
||||
# 3. DISTRIBUTION.
|
||||
# You may, subject to Your compliance with this Agreement, distribute or make available to Third Parties the Tencent Hunyuan Works, exclusively in the Territory, provided that You meet all of the following conditions:
|
||||
# a. You must provide all such Third Party recipients of the Tencent Hunyuan Works or products or services using them a copy of this Agreement;
|
||||
# b. You must cause any modified files to carry prominent notices stating that You changed the files;
|
||||
# c. You are encouraged to: (i) publish at least one technology introduction blogpost or one public statement expressing Your experience of using the Tencent Hunyuan Works; and (ii) mark the products or services developed by using the Tencent Hunyuan Works to indicate that the product/service is “Powered by Tencent Hunyuan”; and
|
||||
# d. All distributions to Third Parties (other than through a Hosted Service) must be accompanied by a “Notice” text file that contains the following notice: “Tencent Hunyuan is licensed under the Tencent Hunyuan Community License Agreement, Copyright © 2024 Tencent. All Rights Reserved. The trademark rights of “Tencent Hunyuan” are owned by Tencent or its affiliate.”
|
||||
# You may add Your own copyright statement to Your modifications and, except as set forth in this Section and in Section 5, may provide additional or different license terms and conditions for use, reproduction, or distribution of Your modifications, or for any such Model Derivatives as a whole, provided Your use, reproduction, modification, distribution, performance and display of the work otherwise complies with the terms and conditions of this Agreement (including as regards the Territory). If You receive Tencent Hunyuan Works from a Licensee as part of an integrated end user product, then this Section 3 of this Agreement will not apply to You.
|
||||
# 4. ADDITIONAL COMMERCIAL TERMS.
|
||||
# If, on the Tencent Hunyuan version release date, the monthly active users of all products or services made available by or for Licensee is greater than 100 million monthly active users in the preceding calendar month, You must request a license from Tencent, which Tencent may grant to You in its sole discretion, and You are not authorized to exercise any of the rights under this Agreement unless or until Tencent otherwise expressly grants You such rights.
|
||||
# 5. RULES OF USE.
|
||||
# a. Your use of the Tencent Hunyuan Works must comply with applicable laws and regulations (including trade compliance laws and regulations) and adhere to the Acceptable Use Policy for the Tencent Hunyuan Works, which is hereby incorporated by reference into this Agreement. You must include the use restrictions referenced in these Sections 5(a) and 5(b) as an enforceable provision in any agreement (e.g., license agreement, terms of use, etc.) governing the use and/or distribution of Tencent Hunyuan Works and You must provide notice to subsequent users to whom You distribute that Tencent Hunyuan Works are subject to the use restrictions in these Sections 5(a) and 5(b).
|
||||
# b. You must not use the Tencent Hunyuan Works or any Output or results of the Tencent Hunyuan Works to improve any other large language model (other than Tencent Hunyuan or Model Derivatives thereof).
|
||||
# c. You must not use, reproduce, modify, distribute, or display the Tencent Hunyuan Works, Output or results of the Tencent Hunyuan Works outside the Territory. Any such use outside the Territory is unlicensed and unauthorized under this Agreement.
|
||||
# 6. INTELLECTUAL PROPERTY.
|
||||
# a. Subject to Tencent’s ownership of Tencent Hunyuan Works made by or for Tencent and intellectual property rights therein, conditioned upon Your compliance with the terms and conditions of this Agreement, as between You and Tencent, You will be the owner of any derivative works and modifications of the Materials and any Model Derivatives that are made by or for You.
|
||||
# b. No trademark licenses are granted under this Agreement, and in connection with the Tencent Hunyuan Works, Licensee may not use any name or mark owned by or associated with Tencent or any of its affiliates, except as required for reasonable and customary use in describing and distributing the Tencent Hunyuan Works. Tencent hereby grants You a license to use “Tencent Hunyuan” (the “Mark”) in the Territory solely as required to comply with the provisions of Section 3(c), provided that You comply with any applicable laws related to trademark protection. All goodwill arising out of Your use of the Mark will inure to the benefit of Tencent.
|
||||
# c. If You commence a lawsuit or other proceedings (including a cross-claim or counterclaim in a lawsuit) against Us or any person or entity alleging that the Materials or any Output, or any portion of any of the foregoing, infringe any intellectual property or other right owned or licensable by You, then all licenses granted to You under this Agreement shall terminate as of the date such lawsuit or other proceeding is filed. You will defend, indemnify and hold harmless Us from and against any claim by any Third Party arising out of or related to Your or the Third Party’s use or distribution of the Tencent Hunyuan Works.
|
||||
# d. Tencent claims no rights in Outputs You generate. You and Your users are solely responsible for Outputs and their subsequent uses.
|
||||
# 7. DISCLAIMERS OF WARRANTY AND LIMITATIONS OF LIABILITY.
|
||||
# a. We are not obligated to support, update, provide training for, or develop any further version of the Tencent Hunyuan Works or to grant any license thereto.
|
||||
# b. UNLESS AND ONLY TO THE EXTENT REQUIRED BY APPLICABLE LAW, THE TENCENT HUNYUAN WORKS AND ANY OUTPUT AND RESULTS THEREFROM ARE PROVIDED “AS IS” WITHOUT ANY EXPRESS OR IMPLIED WARRANTIES OF ANY KIND INCLUDING ANY WARRANTIES OF TITLE, MERCHANTABILITY, NONINFRINGEMENT, COURSE OF DEALING, USAGE OF TRADE, OR FITNESS FOR A PARTICULAR PURPOSE. YOU ARE SOLELY RESPONSIBLE FOR DETERMINING THE APPROPRIATENESS OF USING, REPRODUCING, MODIFYING, PERFORMING, DISPLAYING OR DISTRIBUTING ANY OF THE TENCENT HUNYUAN WORKS OR OUTPUTS AND ASSUME ANY AND ALL RISKS ASSOCIATED WITH YOUR OR A THIRD PARTY’S USE OR DISTRIBUTION OF ANY OF THE TENCENT HUNYUAN WORKS OR OUTPUTS AND YOUR EXERCISE OF RIGHTS AND PERMISSIONS UNDER THIS AGREEMENT.
|
||||
# c. TO THE FULLEST EXTENT PERMITTED BY APPLICABLE LAW, IN NO EVENT SHALL TENCENT OR ITS AFFILIATES BE LIABLE UNDER ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, TORT, NEGLIGENCE, PRODUCTS LIABILITY, OR OTHERWISE, FOR ANY DAMAGES, INCLUDING ANY DIRECT, INDIRECT, SPECIAL, INCIDENTAL, EXEMPLARY, CONSEQUENTIAL OR PUNITIVE DAMAGES, OR LOST PROFITS OF ANY KIND ARISING FROM THIS AGREEMENT OR RELATED TO ANY OF THE TENCENT HUNYUAN WORKS OR OUTPUTS, EVEN IF TENCENT OR ITS AFFILIATES HAVE BEEN ADVISED OF THE POSSIBILITY OF ANY OF THE FOREGOING.
|
||||
# 8. SURVIVAL AND TERMINATION.
|
||||
# a. The term of this Agreement shall commence upon Your acceptance of this Agreement or access to the Materials and will continue in full force and effect until terminated in accordance with the terms and conditions herein.
|
||||
# b. We may terminate this Agreement if You breach any of the terms or conditions of this Agreement. Upon termination of this Agreement, You must promptly delete and cease use of the Tencent Hunyuan Works. Sections 6(a), 6(c), 7 and 9 shall survive the termination of this Agreement.
|
||||
# 9. GOVERNING LAW AND JURISDICTION.
|
||||
# a. This Agreement and any dispute arising out of or relating to it will be governed by the laws of the Hong Kong Special Administrative Region of the People’s Republic of China, without regard to conflict of law principles, and the UN Convention on Contracts for the International Sale of Goods does not apply to this Agreement.
|
||||
# b. Exclusive jurisdiction and venue for any dispute arising out of or relating to this Agreement will be a court of competent jurisdiction in the Hong Kong Special Administrative Region of the People’s Republic of China, and Tencent and Licensee consent to the exclusive jurisdiction of such court with respect to any such dispute.
|
||||
#
|
||||
# EXHIBIT A
|
||||
# ACCEPTABLE USE POLICY
|
||||
|
||||
# Tencent reserves the right to update this Acceptable Use Policy from time to time.
|
||||
# Last modified: [insert date]
|
||||
|
||||
# Tencent endeavors to promote safe and fair use of its tools and features, including Tencent Hunyuan. You agree not to use Tencent Hunyuan or Model Derivatives:
|
||||
# 1. Outside the Territory;
|
||||
# 2. In any way that violates any applicable national, federal, state, local, international or any other law or regulation;
|
||||
# 3. To harm Yourself or others;
|
||||
# 4. To repurpose or distribute output from Tencent Hunyuan or any Model Derivatives to harm Yourself or others;
|
||||
# 5. To override or circumvent the safety guardrails and safeguards We have put in place;
|
||||
# 6. For the purpose of exploiting, harming or attempting to exploit or harm minors in any way;
|
||||
# 7. To generate or disseminate verifiably false information and/or content with the purpose of harming others or influencing elections;
|
||||
# 8. To generate or facilitate false online engagement, including fake reviews and other means of fake online engagement;
|
||||
# 9. To intentionally defame, disparage or otherwise harass others;
|
||||
# 10. To generate and/or disseminate malware (including ransomware) or any other content to be used for the purpose of harming electronic systems;
|
||||
# 11. To generate or disseminate personal identifiable information with the purpose of harming others;
|
||||
# 12. To generate or disseminate information (including images, code, posts, articles), and place the information in any public context (including –through the use of bot generated tweets), without expressly and conspicuously identifying that the information and/or content is machine generated;
|
||||
# 13. To impersonate another individual without consent, authorization, or legal right;
|
||||
# 14. To make high-stakes automated decisions in domains that affect an individual’s safety, rights or wellbeing (e.g., law enforcement, migration, medicine/health, management of critical infrastructure, safety components of products, essential services, credit, employment, housing, education, social scoring, or insurance);
|
||||
# 15. In a manner that violates or disrespects the social ethics and moral standards of other countries or regions;
|
||||
# 16. To perform, facilitate, threaten, incite, plan, promote or encourage violent extremism or terrorism;
|
||||
# 17. For any use intended to discriminate against or harm individuals or groups based on protected characteristics or categories, online or offline social behavior or known or predicted personal or personality characteristics;
|
||||
# 18. To intentionally exploit any of the vulnerabilities of a specific group of persons based on their age, social, physical or mental characteristics, in order to materially distort the behavior of a person pertaining to that group in a manner that causes or is likely to cause that person or another person physical or psychological harm;
|
||||
# 19. For military purposes;
|
||||
# 20. To engage in the unauthorized or unlicensed practice of any profession including, but not limited to, financial, legal, medical/health, or other professional practices.
|
||||
|
||||
# ---- End of Tencent Hunyuan Community License Agreement ----
|
||||
|
||||
# Please note that the use of this code is subject to the terms and conditions
|
||||
# of the Tencent Hunyuan Community License Agreement, including the Acceptable Use Policy.
|
||||
|
||||
from typing import *
|
||||
|
||||
import torch
|
||||
import torch.utils.checkpoint
|
||||
from diffusers.configuration_utils import ConfigMixin, register_to_config
|
||||
from diffusers.loaders import PeftAdapterMixin
|
||||
from diffusers.models.attention import FeedForward
|
||||
from diffusers.models.attention_processor import Attention, AttentionProcessor
|
||||
from diffusers.models.embeddings import (
|
||||
GaussianFourierProjection,
|
||||
TimestepEmbedding,
|
||||
Timesteps,
|
||||
)
|
||||
from diffusers.models.modeling_utils import ModelMixin
|
||||
from diffusers.models.normalization import (
|
||||
AdaLayerNormContinuous,
|
||||
FP32LayerNorm,
|
||||
LayerNorm,
|
||||
)
|
||||
from diffusers.utils import (
|
||||
USE_PEFT_BACKEND,
|
||||
is_torch_version,
|
||||
logging,
|
||||
scale_lora_layers,
|
||||
unscale_lora_layers,
|
||||
)
|
||||
from diffusers.utils.torch_utils import maybe_allow_in_graph
|
||||
from torch import nn
|
||||
|
||||
from ..attention_processor import FusedTripoSGAttnProcessor2_0, TripoSGAttnProcessor2_0, PartCrafterAttnProcessor
|
||||
from .modeling_outputs import Transformer1DModelOutput
|
||||
|
||||
logger = logging.get_logger(__name__) # pylint: disable=invalid-name
|
||||
|
||||
|
||||
@maybe_allow_in_graph
|
||||
class DiTBlock(nn.Module):
|
||||
r"""
|
||||
Transformer block used in Hunyuan-DiT model (https://github.com/Tencent/HunyuanDiT). Allow skip connection and
|
||||
QKNorm
|
||||
|
||||
Parameters:
|
||||
dim (`int`):
|
||||
The number of channels in the input and output.
|
||||
num_attention_heads (`int`):
|
||||
The number of headsto use for multi-head attention.
|
||||
cross_attention_dim (`int`,*optional*):
|
||||
The size of the encoder_hidden_states vector for cross attention.
|
||||
dropout(`float`, *optional*, defaults to 0.0):
|
||||
The dropout probability to use.
|
||||
activation_fn (`str`,*optional*, defaults to `"geglu"`):
|
||||
Activation function to be used in feed-forward. .
|
||||
norm_elementwise_affine (`bool`, *optional*, defaults to `True`):
|
||||
Whether to use learnable elementwise affine parameters for normalization.
|
||||
norm_eps (`float`, *optional*, defaults to 1e-6):
|
||||
A small constant added to the denominator in normalization layers to prevent division by zero.
|
||||
final_dropout (`bool` *optional*, defaults to False):
|
||||
Whether to apply a final dropout after the last feed-forward layer.
|
||||
ff_inner_dim (`int`, *optional*):
|
||||
The size of the hidden layer in the feed-forward block. Defaults to `None`.
|
||||
ff_bias (`bool`, *optional*, defaults to `True`):
|
||||
Whether to use bias in the feed-forward block.
|
||||
skip (`bool`, *optional*, defaults to `False`):
|
||||
Whether to use skip connection. Defaults to `False` for down-blocks and mid-blocks.
|
||||
qk_norm (`bool`, *optional*, defaults to `True`):
|
||||
Whether to use normalization in QK calculation. Defaults to `True`.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
dim: int,
|
||||
num_attention_heads: int,
|
||||
use_self_attention: bool = True,
|
||||
self_attention_norm_type: Optional[str] = None,
|
||||
use_cross_attention: bool = True, # ada layer norm
|
||||
cross_attention_dim: Optional[int] = None,
|
||||
cross_attention_norm_type: Optional[str] = "fp32_layer_norm",
|
||||
dropout=0.0,
|
||||
activation_fn: str = "gelu",
|
||||
norm_type: str = "fp32_layer_norm", # TODO
|
||||
norm_elementwise_affine: bool = True,
|
||||
norm_eps: float = 1e-5,
|
||||
final_dropout: bool = False,
|
||||
ff_inner_dim: Optional[int] = None, # int(dim * 4) if None
|
||||
ff_bias: bool = True,
|
||||
skip: bool = False,
|
||||
skip_concat_front: bool = False, # [x, skip] or [skip, x]
|
||||
skip_norm_last: bool = False, # this is an error
|
||||
qk_norm: bool = True,
|
||||
qkv_bias: bool = True,
|
||||
):
|
||||
super().__init__()
|
||||
|
||||
self.use_self_attention = use_self_attention
|
||||
self.use_cross_attention = use_cross_attention
|
||||
self.skip_concat_front = skip_concat_front
|
||||
self.skip_norm_last = skip_norm_last
|
||||
# Define 3 blocks. Each block has its own normalization layer.
|
||||
# NOTE: when new version comes, check norm2 and norm 3
|
||||
# 1. Self-Attn
|
||||
if use_self_attention:
|
||||
if (
|
||||
self_attention_norm_type == "fp32_layer_norm"
|
||||
or self_attention_norm_type is None
|
||||
):
|
||||
self.norm1 = FP32LayerNorm(dim, norm_eps, norm_elementwise_affine)
|
||||
else:
|
||||
raise NotImplementedError
|
||||
|
||||
self.attn1 = Attention(
|
||||
query_dim=dim,
|
||||
cross_attention_dim=None,
|
||||
dim_head=dim // num_attention_heads,
|
||||
heads=num_attention_heads,
|
||||
qk_norm="rms_norm" if qk_norm else None,
|
||||
eps=1e-6,
|
||||
bias=qkv_bias,
|
||||
processor=TripoSGAttnProcessor2_0(),
|
||||
)
|
||||
|
||||
# 2. Cross-Attn
|
||||
if use_cross_attention:
|
||||
assert cross_attention_dim is not None
|
||||
|
||||
self.norm2 = FP32LayerNorm(dim, norm_eps, norm_elementwise_affine)
|
||||
|
||||
self.attn2 = Attention(
|
||||
query_dim=dim,
|
||||
cross_attention_dim=cross_attention_dim,
|
||||
dim_head=dim // num_attention_heads,
|
||||
heads=num_attention_heads,
|
||||
qk_norm="rms_norm" if qk_norm else None,
|
||||
cross_attention_norm=cross_attention_norm_type,
|
||||
eps=1e-6,
|
||||
bias=qkv_bias,
|
||||
processor=TripoSGAttnProcessor2_0(),
|
||||
)
|
||||
|
||||
# 3. Feed-forward
|
||||
self.norm3 = FP32LayerNorm(dim, norm_eps, norm_elementwise_affine)
|
||||
|
||||
self.ff = FeedForward(
|
||||
dim,
|
||||
dropout=dropout, ### 0.0
|
||||
activation_fn=activation_fn, ### approx GeLU
|
||||
final_dropout=final_dropout, ### 0.0
|
||||
inner_dim=ff_inner_dim, ### int(dim * mlp_ratio)
|
||||
bias=ff_bias,
|
||||
)
|
||||
|
||||
# 4. Skip Connection
|
||||
if skip:
|
||||
self.skip_norm = FP32LayerNorm(dim, norm_eps, elementwise_affine=True)
|
||||
self.skip_linear = nn.Linear(2 * dim, dim)
|
||||
else:
|
||||
self.skip_linear = None
|
||||
|
||||
# let chunk size default to None
|
||||
self._chunk_size = None
|
||||
self._chunk_dim = 0
|
||||
|
||||
def set_topk(self, topk):
|
||||
self.flash_processor.topk = topk
|
||||
|
||||
def set_flash_processor(self, flash_processor):
|
||||
self.flash_processor = flash_processor
|
||||
self.attn2.processor = self.flash_processor
|
||||
|
||||
# Copied from diffusers.models.attention.BasicTransformerBlock.set_chunk_feed_forward
|
||||
def set_chunk_feed_forward(self, chunk_size: Optional[int], dim: int = 0):
|
||||
# Sets chunk feed-forward
|
||||
self._chunk_size = chunk_size
|
||||
self._chunk_dim = dim
|
||||
|
||||
def forward(
|
||||
self,
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: Optional[torch.Tensor] = None,
|
||||
temb: Optional[torch.Tensor] = None,
|
||||
image_rotary_emb: Optional[torch.Tensor] = None,
|
||||
skip: Optional[torch.Tensor] = None,
|
||||
attention_kwargs: Optional[Dict[str, Any]] = None,
|
||||
) -> torch.Tensor:
|
||||
# Prepare attention kwargs
|
||||
attention_kwargs = attention_kwargs or {}
|
||||
|
||||
# Notice that normalization is always applied before the real computation in the following blocks.
|
||||
# 0. Long Skip Connection
|
||||
if self.skip_linear is not None:
|
||||
cat = torch.cat(
|
||||
(
|
||||
[skip, hidden_states]
|
||||
if self.skip_concat_front
|
||||
else [hidden_states, skip]
|
||||
),
|
||||
dim=-1,
|
||||
)
|
||||
if self.skip_norm_last:
|
||||
# don't do this
|
||||
hidden_states = self.skip_linear(cat)
|
||||
hidden_states = self.skip_norm(hidden_states)
|
||||
else:
|
||||
cat = self.skip_norm(cat)
|
||||
hidden_states = self.skip_linear(cat)
|
||||
|
||||
# 1. Self-Attention
|
||||
if self.use_self_attention:
|
||||
norm_hidden_states = self.norm1(hidden_states)
|
||||
attn_output = self.attn1(
|
||||
norm_hidden_states,
|
||||
image_rotary_emb=image_rotary_emb,
|
||||
**attention_kwargs,
|
||||
)
|
||||
hidden_states = hidden_states + attn_output
|
||||
|
||||
# 2. Cross-Attention
|
||||
if self.use_cross_attention:
|
||||
hidden_states = hidden_states + self.attn2(
|
||||
self.norm2(hidden_states),
|
||||
encoder_hidden_states=encoder_hidden_states,
|
||||
image_rotary_emb=image_rotary_emb,
|
||||
**attention_kwargs,
|
||||
)
|
||||
|
||||
# FFN Layer ### TODO: switch norm2 and norm3 in the state dict
|
||||
mlp_inputs = self.norm3(hidden_states)
|
||||
hidden_states = hidden_states + self.ff(mlp_inputs)
|
||||
|
||||
return hidden_states
|
||||
|
||||
# Modified from https://github.com/VAST-AI-Research/TripoSG/blob/main/triposg/models/transformers/triposg_transformer.py#L365
|
||||
class PartCrafterDiTModel(ModelMixin, ConfigMixin, PeftAdapterMixin):
|
||||
"""
|
||||
TripoSG: Diffusion model with a Transformer backbone.
|
||||
|
||||
Inherit ModelMixin and ConfigMixin to be compatible with the sampler StableDiffusionPipeline of diffusers.
|
||||
|
||||
Parameters:
|
||||
num_attention_heads (`int`, *optional*, defaults to 16):
|
||||
The number of heads to use for multi-head attention.
|
||||
attention_head_dim (`int`, *optional*, defaults to 88):
|
||||
The number of channels in each head.
|
||||
in_channels (`int`, *optional*):
|
||||
The number of channels in the input and output (specify if the input is **continuous**).
|
||||
patch_size (`int`, *optional*):
|
||||
The size of the patch to use for the input.
|
||||
activation_fn (`str`, *optional*, defaults to `"geglu"`):
|
||||
Activation function to use in feed-forward.
|
||||
sample_size (`int`, *optional*):
|
||||
The width of the latent images. This is fixed during training since it is used to learn a number of
|
||||
position embeddings.
|
||||
dropout (`float`, *optional*, defaults to 0.0):
|
||||
The dropout probability to use.
|
||||
cross_attention_dim (`int`, *optional*):
|
||||
The number of dimension in the clip text embedding.
|
||||
hidden_size (`int`, *optional*):
|
||||
The size of hidden layer in the conditioning embedding layers.
|
||||
num_layers (`int`, *optional*, defaults to 1):
|
||||
The number of layers of Transformer blocks to use.
|
||||
mlp_ratio (`float`, *optional*, defaults to 4.0):
|
||||
The ratio of the hidden layer size to the input size.
|
||||
learn_sigma (`bool`, *optional*, defaults to `True`):
|
||||
Whether to predict variance.
|
||||
cross_attention_dim_t5 (`int`, *optional*):
|
||||
The number dimensions in t5 text embedding.
|
||||
pooled_projection_dim (`int`, *optional*):
|
||||
The size of the pooled projection.
|
||||
text_len (`int`, *optional*):
|
||||
The length of the clip text embedding.
|
||||
text_len_t5 (`int`, *optional*):
|
||||
The length of the T5 text embedding.
|
||||
use_style_cond_and_image_meta_size (`bool`, *optional*):
|
||||
Whether or not to use style condition and image meta size. True for version <=1.1, False for version >= 1.2
|
||||
"""
|
||||
|
||||
_supports_gradient_checkpointing = True
|
||||
|
||||
@register_to_config
|
||||
def __init__(
|
||||
self,
|
||||
num_attention_heads: int = 16,
|
||||
width: int = 2048,
|
||||
in_channels: int = 64,
|
||||
num_layers: int = 21,
|
||||
cross_attention_dim: int = 1024,
|
||||
max_num_parts: int = 32,
|
||||
enable_part_embedding=True,
|
||||
enable_local_cross_attn: bool = True,
|
||||
enable_global_cross_attn: bool = True,
|
||||
global_attn_block_ids: Optional[List[int]] = None,
|
||||
global_attn_block_id_range: Optional[List[int]] = None,
|
||||
):
|
||||
super().__init__()
|
||||
self.out_channels = in_channels
|
||||
self.num_heads = num_attention_heads
|
||||
self.inner_dim = width
|
||||
self.mlp_ratio = 4.0
|
||||
|
||||
time_embed_dim, timestep_input_dim = self._set_time_proj(
|
||||
"positional",
|
||||
inner_dim=self.inner_dim,
|
||||
flip_sin_to_cos=False,
|
||||
freq_shift=0,
|
||||
time_embedding_dim=None,
|
||||
)
|
||||
self.time_proj = TimestepEmbedding(
|
||||
timestep_input_dim, time_embed_dim, act_fn="gelu", out_dim=self.inner_dim
|
||||
)
|
||||
|
||||
if enable_part_embedding:
|
||||
self.part_embedding = nn.Embedding(max_num_parts, self.inner_dim)
|
||||
self.part_embedding.weight.data.normal_(mean=0.0, std=0.02)
|
||||
self.enable_part_embedding = enable_part_embedding
|
||||
|
||||
self.proj_in = nn.Linear(self.config.in_channels, self.inner_dim, bias=True)
|
||||
|
||||
self.blocks = nn.ModuleList(
|
||||
[
|
||||
DiTBlock(
|
||||
dim=self.inner_dim,
|
||||
num_attention_heads=self.config.num_attention_heads,
|
||||
use_self_attention=True,
|
||||
self_attention_norm_type="fp32_layer_norm",
|
||||
use_cross_attention=True,
|
||||
cross_attention_dim=cross_attention_dim,
|
||||
cross_attention_norm_type=None,
|
||||
activation_fn="gelu",
|
||||
norm_type="fp32_layer_norm", # TODO
|
||||
norm_eps=1e-5,
|
||||
ff_inner_dim=int(self.inner_dim * self.mlp_ratio),
|
||||
skip=layer > num_layers // 2,
|
||||
skip_concat_front=True,
|
||||
skip_norm_last=True, # this is an error
|
||||
qk_norm=True, # See http://arxiv.org/abs/2302.05442 for details.
|
||||
qkv_bias=False,
|
||||
)
|
||||
for layer in range(num_layers)
|
||||
]
|
||||
)
|
||||
|
||||
self.norm_out = LayerNorm(self.inner_dim)
|
||||
self.proj_out = nn.Linear(self.inner_dim, self.out_channels, bias=True)
|
||||
|
||||
self.gradient_checkpointing = False
|
||||
|
||||
self.enable_local_cross_attn = enable_local_cross_attn
|
||||
self.enable_global_cross_attn = enable_global_cross_attn
|
||||
|
||||
if global_attn_block_ids is None:
|
||||
global_attn_block_ids = []
|
||||
if global_attn_block_id_range is not None:
|
||||
global_attn_block_ids = list(range(global_attn_block_id_range[0], global_attn_block_id_range[1] + 1))
|
||||
self.global_attn_block_ids = global_attn_block_ids
|
||||
|
||||
if len(global_attn_block_ids) > 0:
|
||||
# Override self-attention processors for global attention blocks
|
||||
attn_processor_dict = {}
|
||||
modified_attn_processor = []
|
||||
for layer_id in range(num_layers):
|
||||
for attn_id in [1, 2]:
|
||||
if layer_id in global_attn_block_ids:
|
||||
# apply to both self-attention and cross-attention
|
||||
attn_processor_dict[f'blocks.{layer_id}.attn{attn_id}.processor'] = PartCrafterAttnProcessor()
|
||||
modified_attn_processor.append(f'blocks.{layer_id}.attn{attn_id}.processor')
|
||||
else:
|
||||
attn_processor_dict[f'blocks.{layer_id}.attn{attn_id}.processor'] = TripoSGAttnProcessor2_0()
|
||||
self.set_attn_processor(attn_processor_dict)
|
||||
# logger.info(f"Modified {modified_attn_processor} to PartCrafterAttnProcessor")
|
||||
|
||||
def _set_gradient_checkpointing(
|
||||
self,
|
||||
enable: bool = False,
|
||||
gradient_checkpointing_func: Optional[Callable] = None,
|
||||
):
|
||||
# TODO: implement gradient checkpointing
|
||||
self.gradient_checkpointing = enable
|
||||
|
||||
def _set_time_proj(
|
||||
self,
|
||||
time_embedding_type: str,
|
||||
inner_dim: int,
|
||||
flip_sin_to_cos: bool,
|
||||
freq_shift: float,
|
||||
time_embedding_dim: int,
|
||||
) -> Tuple[int, int]:
|
||||
if time_embedding_type == "fourier":
|
||||
time_embed_dim = time_embedding_dim or inner_dim * 2
|
||||
if time_embed_dim % 2 != 0:
|
||||
raise ValueError(
|
||||
f"`time_embed_dim` should be divisible by 2, but is {time_embed_dim}."
|
||||
)
|
||||
self.time_embed = GaussianFourierProjection(
|
||||
time_embed_dim // 2,
|
||||
set_W_to_weight=False,
|
||||
log=False,
|
||||
flip_sin_to_cos=flip_sin_to_cos,
|
||||
)
|
||||
timestep_input_dim = time_embed_dim
|
||||
elif time_embedding_type == "positional":
|
||||
time_embed_dim = time_embedding_dim or inner_dim * 4
|
||||
|
||||
self.time_embed = Timesteps(inner_dim, flip_sin_to_cos, freq_shift)
|
||||
timestep_input_dim = inner_dim
|
||||
else:
|
||||
raise ValueError(
|
||||
f"{time_embedding_type} does not exist. Please make sure to use one of `fourier` or `positional`."
|
||||
)
|
||||
|
||||
return time_embed_dim, timestep_input_dim
|
||||
|
||||
# Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.fuse_qkv_projections with FusedAttnProcessor2_0->FusedTripoSGAttnProcessor2_0
|
||||
def fuse_qkv_projections(self):
|
||||
"""
|
||||
Enables fused QKV projections. For self-attention modules, all projection matrices (i.e., query, key, value)
|
||||
are fused. For cross-attention modules, key and value projection matrices are fused.
|
||||
|
||||
<Tip warning={true}>
|
||||
|
||||
This API is 🧪 experimental.
|
||||
|
||||
</Tip>
|
||||
"""
|
||||
self.original_attn_processors = None
|
||||
|
||||
for _, attn_processor in self.attn_processors.items():
|
||||
if "Added" in str(attn_processor.__class__.__name__):
|
||||
raise ValueError(
|
||||
"`fuse_qkv_projections()` is not supported for models having added KV projections."
|
||||
)
|
||||
|
||||
self.original_attn_processors = self.attn_processors
|
||||
|
||||
for module in self.modules():
|
||||
if isinstance(module, Attention):
|
||||
module.fuse_projections(fuse=True)
|
||||
|
||||
self.set_attn_processor(FusedTripoSGAttnProcessor2_0())
|
||||
|
||||
# Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.unfuse_qkv_projections
|
||||
def unfuse_qkv_projections(self):
|
||||
"""Disables the fused QKV projection if enabled.
|
||||
|
||||
<Tip warning={true}>
|
||||
|
||||
This API is 🧪 experimental.
|
||||
|
||||
</Tip>
|
||||
|
||||
"""
|
||||
if self.original_attn_processors is not None:
|
||||
self.set_attn_processor(self.original_attn_processors)
|
||||
|
||||
@property
|
||||
# Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.attn_processors
|
||||
def attn_processors(self) -> Dict[str, AttentionProcessor]:
|
||||
r"""
|
||||
Returns:
|
||||
`dict` of attention processors: A dictionary containing all attention processors used in the model with
|
||||
indexed by its weight name.
|
||||
"""
|
||||
# set recursively
|
||||
processors = {}
|
||||
|
||||
def fn_recursive_add_processors(
|
||||
name: str,
|
||||
module: torch.nn.Module,
|
||||
processors: Dict[str, AttentionProcessor],
|
||||
):
|
||||
if hasattr(module, "get_processor"):
|
||||
processors[f"{name}.processor"] = module.get_processor()
|
||||
|
||||
for sub_name, child in module.named_children():
|
||||
fn_recursive_add_processors(f"{name}.{sub_name}", child, processors)
|
||||
|
||||
return processors
|
||||
|
||||
for name, module in self.named_children():
|
||||
fn_recursive_add_processors(name, module, processors)
|
||||
|
||||
return processors
|
||||
|
||||
# Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.set_attn_processor
|
||||
def set_attn_processor(
|
||||
self, processor: Union[AttentionProcessor, Dict[str, AttentionProcessor]]
|
||||
):
|
||||
r"""
|
||||
Sets the attention processor to use to compute attention.
|
||||
|
||||
Parameters:
|
||||
processor (`dict` of `AttentionProcessor` or only `AttentionProcessor`):
|
||||
The instantiated processor class or a dictionary of processor classes that will be set as the processor
|
||||
for **all** `Attention` layers.
|
||||
|
||||
If `processor` is a dict, the key needs to define the path to the corresponding cross attention
|
||||
processor. This is strongly recommended when setting trainable attention processors.
|
||||
|
||||
"""
|
||||
count = len(self.attn_processors.keys())
|
||||
|
||||
if isinstance(processor, dict) and len(processor) != count:
|
||||
raise ValueError(
|
||||
f"A dict of processors was passed, but the number of processors {len(processor)} does not match the"
|
||||
f" number of attention layers: {count}. Please make sure to pass {count} processor classes."
|
||||
)
|
||||
|
||||
def fn_recursive_attn_processor(name: str, module: torch.nn.Module, processor):
|
||||
if hasattr(module, "set_processor"):
|
||||
if not isinstance(processor, dict):
|
||||
module.set_processor(processor)
|
||||
else:
|
||||
module.set_processor(processor.pop(f"{name}.processor"))
|
||||
|
||||
for sub_name, child in module.named_children():
|
||||
fn_recursive_attn_processor(f"{name}.{sub_name}", child, processor)
|
||||
|
||||
for name, module in self.named_children():
|
||||
fn_recursive_attn_processor(name, module, processor)
|
||||
|
||||
def set_default_attn_processor(self):
|
||||
"""
|
||||
Disables custom attention processors and sets the default attention implementation.
|
||||
"""
|
||||
self.set_attn_processor(TripoSGAttnProcessor2_0())
|
||||
|
||||
def forward(
|
||||
self,
|
||||
hidden_states: Optional[torch.Tensor],
|
||||
timestep: Union[int, float, torch.LongTensor],
|
||||
encoder_hidden_states: Optional[torch.Tensor] = None,
|
||||
image_rotary_emb: Optional[Tuple[torch.Tensor, torch.Tensor]] = None,
|
||||
attention_kwargs: Optional[Dict[str, Any]] = None,
|
||||
return_dict: bool = True,
|
||||
):
|
||||
"""
|
||||
The [`HunyuanDiT2DModel`] forward method.
|
||||
|
||||
Args:
|
||||
hidden_states (`torch.Tensor` of shape `(batch size, dim, height, width)`):
|
||||
The input tensor.
|
||||
timestep ( `torch.LongTensor`, *optional*):
|
||||
Used to indicate denoising step.
|
||||
encoder_hidden_states ( `torch.Tensor` of shape `(batch size, sequence len, embed dims)`, *optional*):
|
||||
Conditional embeddings for cross attention layer.
|
||||
return_dict: bool
|
||||
Whether to return a dictionary.
|
||||
"""
|
||||
|
||||
if attention_kwargs is not None:
|
||||
attention_kwargs = attention_kwargs.copy()
|
||||
lora_scale = attention_kwargs.pop("scale", 1.0)
|
||||
else:
|
||||
lora_scale = 1.0
|
||||
|
||||
if USE_PEFT_BACKEND:
|
||||
# weight the lora layers by setting `lora_scale` for each PEFT layer
|
||||
scale_lora_layers(self, lora_scale)
|
||||
else:
|
||||
if (
|
||||
attention_kwargs is not None
|
||||
and attention_kwargs.get("scale", None) is not None
|
||||
):
|
||||
logger.warning(
|
||||
"Passing `scale` via `attention_kwargs` when not using the PEFT backend is ineffective."
|
||||
)
|
||||
|
||||
_, T, _ = hidden_states.shape
|
||||
|
||||
temb = self.time_embed(timestep).to(hidden_states.dtype)
|
||||
temb = self.time_proj(temb)
|
||||
temb = temb.unsqueeze(dim=1) # unsqueeze to concat with hidden_states
|
||||
|
||||
hidden_states = self.proj_in(hidden_states)
|
||||
|
||||
# T + 1 token
|
||||
hidden_states = torch.cat([temb, hidden_states], dim=1) # (N, T+1, D)
|
||||
|
||||
if self.enable_part_embedding:
|
||||
# Add part embedding
|
||||
num_parts = attention_kwargs["num_parts"]
|
||||
if isinstance(num_parts, torch.Tensor):
|
||||
part_embeddings = []
|
||||
for num_part in num_parts:
|
||||
part_embedding = self.part_embedding(torch.arange(num_part, device=hidden_states.device)) # (n, D)
|
||||
part_embeddings.append(part_embedding)
|
||||
part_embedding = torch.cat(part_embeddings, dim=0) # (N, D)
|
||||
elif isinstance(num_parts, int):
|
||||
part_embedding = self.part_embedding(torch.arange(hidden_states.shape[0], device=hidden_states.device)) # (N, D)
|
||||
else:
|
||||
raise ValueError(
|
||||
"num_parts must be a torch.Tensor or int, but got {}".format(type(num_parts))
|
||||
)
|
||||
hidden_states = hidden_states + part_embedding.unsqueeze(dim=1) # (N, T+1, D)
|
||||
|
||||
# prepare negative encoder_hidden_states
|
||||
negative_encoder_hidden_states = torch.zeros_like(encoder_hidden_states) if encoder_hidden_states is not None else None
|
||||
|
||||
skips = []
|
||||
for layer, block in enumerate(self.blocks):
|
||||
skip = None if layer <= self.config.num_layers // 2 else skips.pop()
|
||||
if (
|
||||
(not self.enable_local_cross_attn)
|
||||
and len(self.global_attn_block_ids) > 0
|
||||
and (layer not in self.global_attn_block_ids)
|
||||
):
|
||||
# If in non-global attention block and disable local cross attention, use negative encoder_hidden_states
|
||||
# Do not inject control signal into non-global attention block
|
||||
input_encoder_hidden_states = negative_encoder_hidden_states
|
||||
elif (
|
||||
(not self.enable_global_cross_attn)
|
||||
and len(self.global_attn_block_ids) > 0
|
||||
and (layer in self.global_attn_block_ids)
|
||||
):
|
||||
# If in global attention block and disable global cross attention, use negative encoder_hidden_states
|
||||
# Do not inject control signal into global attention block
|
||||
input_encoder_hidden_states = negative_encoder_hidden_states
|
||||
else:
|
||||
input_encoder_hidden_states = encoder_hidden_states
|
||||
|
||||
if len(self.global_attn_block_ids) > 0 and (layer in self.global_attn_block_ids):
|
||||
# Inject control signal into global attention block
|
||||
input_attention_kwargs = attention_kwargs
|
||||
else:
|
||||
input_attention_kwargs = None
|
||||
|
||||
if self.training and self.gradient_checkpointing:
|
||||
|
||||
def create_custom_forward(module):
|
||||
def custom_forward(*inputs):
|
||||
return module(*inputs)
|
||||
|
||||
return custom_forward
|
||||
|
||||
ckpt_kwargs: Dict[str, Any] = (
|
||||
{"use_reentrant": False} if is_torch_version(">=", "1.11.0") else {}
|
||||
)
|
||||
hidden_states = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(block),
|
||||
hidden_states,
|
||||
input_encoder_hidden_states,
|
||||
temb,
|
||||
image_rotary_emb,
|
||||
skip,
|
||||
input_attention_kwargs,
|
||||
**ckpt_kwargs,
|
||||
)
|
||||
else:
|
||||
hidden_states = block(
|
||||
hidden_states,
|
||||
encoder_hidden_states=input_encoder_hidden_states,
|
||||
temb=temb,
|
||||
image_rotary_emb=image_rotary_emb,
|
||||
skip=skip,
|
||||
attention_kwargs=input_attention_kwargs,
|
||||
) # (N, T+1, D)
|
||||
|
||||
if layer < self.config.num_layers // 2:
|
||||
skips.append(hidden_states)
|
||||
|
||||
# final layer
|
||||
hidden_states = self.norm_out(hidden_states)
|
||||
hidden_states = hidden_states[:, -T:] # (N, T, D)
|
||||
hidden_states = self.proj_out(hidden_states)
|
||||
|
||||
if USE_PEFT_BACKEND:
|
||||
# remove `lora_scale` from each PEFT layer
|
||||
unscale_lora_layers(self, lora_scale)
|
||||
|
||||
if not return_dict:
|
||||
return (hidden_states,)
|
||||
|
||||
return Transformer1DModelOutput(sample=hidden_states)
|
||||
|
||||
# Copied from diffusers.models.unets.unet_3d_condition.UNet3DConditionModel.enable_forward_chunking
|
||||
def enable_forward_chunking(
|
||||
self, chunk_size: Optional[int] = None, dim: int = 0
|
||||
) -> None:
|
||||
"""
|
||||
Sets the attention processor to use [feed forward
|
||||
chunking](https://huggingface.co/blog/reformer#2-chunked-feed-forward-layers).
|
||||
|
||||
Parameters:
|
||||
chunk_size (`int`, *optional*):
|
||||
The chunk size of the feed-forward layers. If not specified, will run feed-forward layer individually
|
||||
over each tensor of dim=`dim`.
|
||||
dim (`int`, *optional*, defaults to `0`):
|
||||
The dimension over which the feed-forward computation should be chunked. Choose between dim=0 (batch)
|
||||
or dim=1 (sequence length).
|
||||
"""
|
||||
if dim not in [0, 1]:
|
||||
raise ValueError(f"Make sure to set `dim` to either 0 or 1, not {dim}")
|
||||
|
||||
# By default chunk size is 1
|
||||
chunk_size = chunk_size or 1
|
||||
|
||||
def fn_recursive_feed_forward(
|
||||
module: torch.nn.Module, chunk_size: int, dim: int
|
||||
):
|
||||
if hasattr(module, "set_chunk_feed_forward"):
|
||||
module.set_chunk_feed_forward(chunk_size=chunk_size, dim=dim)
|
||||
|
||||
for child in module.children():
|
||||
fn_recursive_feed_forward(child, chunk_size, dim)
|
||||
|
||||
for module in self.children():
|
||||
fn_recursive_feed_forward(module, chunk_size, dim)
|
||||
|
||||
# Copied from diffusers.models.unets.unet_3d_condition.UNet3DConditionModel.disable_forward_chunking
|
||||
def disable_forward_chunking(self):
|
||||
def fn_recursive_feed_forward(
|
||||
module: torch.nn.Module, chunk_size: int, dim: int
|
||||
):
|
||||
if hasattr(module, "set_chunk_feed_forward"):
|
||||
module.set_chunk_feed_forward(chunk_size=chunk_size, dim=dim)
|
||||
|
||||
for child in module.children():
|
||||
fn_recursive_feed_forward(child, chunk_size, dim)
|
||||
|
||||
for module in self.children():
|
||||
fn_recursive_feed_forward(module, None, 0)
|
||||
+355
@@ -0,0 +1,355 @@
|
||||
import inspect
|
||||
import math
|
||||
from typing import Any, Callable, Dict, List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
import PIL
|
||||
import PIL.Image
|
||||
import torch
|
||||
import trimesh
|
||||
from diffusers.image_processor import PipelineImageInput
|
||||
from diffusers.pipelines.pipeline_utils import DiffusionPipeline
|
||||
from diffusers.schedulers import FlowMatchEulerDiscreteScheduler
|
||||
from diffusers.utils import logging
|
||||
from diffusers.utils.torch_utils import randn_tensor
|
||||
from transformers import (
|
||||
BitImageProcessor,
|
||||
Dinov2Model,
|
||||
)
|
||||
from ..utils.inference_utils import hierarchical_extract_geometry
|
||||
|
||||
from ..models.autoencoders import TripoSGVAEModel
|
||||
from ..models.transformers import PartCrafterDiTModel
|
||||
from .pipeline_partcrafter_output import PartCrafterPipelineOutput
|
||||
from .pipeline_utils import TransformerDiffusionMixin
|
||||
|
||||
logger = logging.get_logger(__name__) # pylint: disable=invalid-name
|
||||
|
||||
|
||||
# Copied from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion.retrieve_timesteps
|
||||
def retrieve_timesteps(
|
||||
scheduler,
|
||||
num_inference_steps: Optional[int] = None,
|
||||
device: Optional[Union[str, torch.device]] = None,
|
||||
timesteps: Optional[List[int]] = None,
|
||||
sigmas: Optional[List[float]] = None,
|
||||
**kwargs,
|
||||
):
|
||||
"""
|
||||
Calls the scheduler's `set_timesteps` method and retrieves timesteps from the scheduler after the call. Handles
|
||||
custom timesteps. Any kwargs will be supplied to `scheduler.set_timesteps`.
|
||||
|
||||
Args:
|
||||
scheduler (`SchedulerMixin`):
|
||||
The scheduler to get timesteps from.
|
||||
num_inference_steps (`int`):
|
||||
The number of diffusion steps used when generating samples with a pre-trained model. If used, `timesteps`
|
||||
must be `None`.
|
||||
device (`str` or `torch.device`, *optional*):
|
||||
The device to which the timesteps should be moved to. If `None`, the timesteps are not moved.
|
||||
timesteps (`List[int]`, *optional*):
|
||||
Custom timesteps used to override the timestep spacing strategy of the scheduler. If `timesteps` is passed,
|
||||
`num_inference_steps` and `sigmas` must be `None`.
|
||||
sigmas (`List[float]`, *optional*):
|
||||
Custom sigmas used to override the timestep spacing strategy of the scheduler. If `sigmas` is passed,
|
||||
`num_inference_steps` and `timesteps` must be `None`.
|
||||
|
||||
Returns:
|
||||
`Tuple[torch.Tensor, int]`: A tuple where the first element is the timestep schedule from the scheduler and the
|
||||
second element is the number of inference steps.
|
||||
"""
|
||||
if timesteps is not None and sigmas is not None:
|
||||
raise ValueError(
|
||||
"Only one of `timesteps` or `sigmas` can be passed. Please choose one to set custom values"
|
||||
)
|
||||
if timesteps is not None:
|
||||
accepts_timesteps = "timesteps" in set(
|
||||
inspect.signature(scheduler.set_timesteps).parameters.keys()
|
||||
)
|
||||
if not accepts_timesteps:
|
||||
raise ValueError(
|
||||
f"The current scheduler class {scheduler.__class__}'s `set_timesteps` does not support custom"
|
||||
f" timestep schedules. Please check whether you are using the correct scheduler."
|
||||
)
|
||||
scheduler.set_timesteps(timesteps=timesteps, device=device, **kwargs)
|
||||
timesteps = scheduler.timesteps
|
||||
num_inference_steps = len(timesteps)
|
||||
elif sigmas is not None:
|
||||
accept_sigmas = "sigmas" in set(
|
||||
inspect.signature(scheduler.set_timesteps).parameters.keys()
|
||||
)
|
||||
if not accept_sigmas:
|
||||
raise ValueError(
|
||||
f"The current scheduler class {scheduler.__class__}'s `set_timesteps` does not support custom"
|
||||
f" sigmas schedules. Please check whether you are using the correct scheduler."
|
||||
)
|
||||
scheduler.set_timesteps(sigmas=sigmas, device=device, **kwargs)
|
||||
timesteps = scheduler.timesteps
|
||||
num_inference_steps = len(timesteps)
|
||||
else:
|
||||
scheduler.set_timesteps(num_inference_steps, device=device, **kwargs)
|
||||
timesteps = scheduler.timesteps
|
||||
return timesteps, num_inference_steps
|
||||
|
||||
|
||||
class PartCrafterPipeline(DiffusionPipeline, TransformerDiffusionMixin):
|
||||
"""
|
||||
Pipeline for image to 3D part-level object generation.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
vae: TripoSGVAEModel,
|
||||
transformer: PartCrafterDiTModel,
|
||||
scheduler: FlowMatchEulerDiscreteScheduler,
|
||||
image_encoder_dinov2: Dinov2Model,
|
||||
feature_extractor_dinov2: BitImageProcessor,
|
||||
):
|
||||
super().__init__()
|
||||
|
||||
self.register_modules(
|
||||
vae=vae,
|
||||
transformer=transformer,
|
||||
scheduler=scheduler,
|
||||
image_encoder_dinov2=image_encoder_dinov2,
|
||||
feature_extractor_dinov2=feature_extractor_dinov2,
|
||||
)
|
||||
|
||||
@property
|
||||
def guidance_scale(self):
|
||||
return self._guidance_scale
|
||||
|
||||
@property
|
||||
def do_classifier_free_guidance(self):
|
||||
return self._guidance_scale > 1
|
||||
|
||||
@property
|
||||
def num_timesteps(self):
|
||||
return self._num_timesteps
|
||||
|
||||
@property
|
||||
def attention_kwargs(self):
|
||||
return self._attention_kwargs
|
||||
|
||||
@property
|
||||
def interrupt(self):
|
||||
return self._interrupt
|
||||
|
||||
@property
|
||||
def decode_progressive(self):
|
||||
return self._decode_progressive
|
||||
|
||||
def encode_image(self, image, device, num_images_per_prompt):
|
||||
dtype = next(self.image_encoder_dinov2.parameters()).dtype
|
||||
|
||||
if not isinstance(image, torch.Tensor):
|
||||
image = self.feature_extractor_dinov2(image, return_tensors="pt").pixel_values
|
||||
|
||||
image = image.to(device=device, dtype=dtype)
|
||||
image_embeds = self.image_encoder_dinov2(image).last_hidden_state
|
||||
image_embeds = image_embeds.repeat_interleave(num_images_per_prompt, dim=0)
|
||||
uncond_image_embeds = torch.zeros_like(image_embeds)
|
||||
|
||||
return image_embeds, uncond_image_embeds
|
||||
|
||||
def prepare_latents(
|
||||
self,
|
||||
batch_size,
|
||||
num_tokens,
|
||||
num_channels_latents,
|
||||
dtype,
|
||||
device,
|
||||
generator,
|
||||
latents: Optional[torch.Tensor] = None,
|
||||
):
|
||||
shape = (batch_size, num_tokens, num_channels_latents)
|
||||
|
||||
if isinstance(generator, list) and len(generator) != batch_size:
|
||||
raise ValueError(
|
||||
f"You have passed a list of generators of length {len(generator)}, but requested an effective batch"
|
||||
f" size of {batch_size}. Make sure the batch size matches the length of the generators."
|
||||
)
|
||||
|
||||
noise = randn_tensor(shape, generator=generator, device=device, dtype=dtype)
|
||||
return noise
|
||||
|
||||
@torch.no_grad()
|
||||
def __call__(
|
||||
self,
|
||||
image: PipelineImageInput,
|
||||
num_inference_steps: int = 50,
|
||||
num_tokens: int = 2048,
|
||||
timesteps: List[int] = None,
|
||||
guidance_scale: float = 7.0,
|
||||
num_images_per_prompt: int = 1,
|
||||
generator: Optional[Union[torch.Generator, List[torch.Generator]]] = None,
|
||||
latents: Optional[torch.FloatTensor] = None,
|
||||
attention_kwargs: Optional[Dict[str, Any]] = None,
|
||||
callback_on_step_end: Optional[Callable[[int, int, Dict], None]] = None,
|
||||
callback_on_step_end_tensor_inputs: List[str] = ["latents"],
|
||||
bounds: Union[Tuple[float], List[float], float] = (-1.005, -1.005, -1.005, 1.005, 1.005, 1.005),
|
||||
dense_octree_depth: int = 8,
|
||||
hierarchical_octree_depth: int = 9,
|
||||
max_num_expanded_coords: int = 1e8,
|
||||
flash_octree_depth: int = 9,
|
||||
use_flash_decoder: bool = True,
|
||||
return_dict: bool = True,
|
||||
):
|
||||
# 1. Define call parameters
|
||||
self._guidance_scale = guidance_scale
|
||||
self._attention_kwargs = attention_kwargs
|
||||
self._interrupt = False
|
||||
|
||||
# 2. Define call parameters
|
||||
if isinstance(image, PIL.Image.Image):
|
||||
batch_size = 1
|
||||
elif isinstance(image, list):
|
||||
batch_size = len(image)
|
||||
elif isinstance(image, torch.Tensor):
|
||||
batch_size = image.shape[0]
|
||||
else:
|
||||
raise ValueError("Invalid input type for image")
|
||||
|
||||
device = self._execution_device
|
||||
dtype = self.image_encoder_dinov2.dtype
|
||||
|
||||
# 3. Encode condition
|
||||
image_embeds, negative_image_embeds = self.encode_image(
|
||||
image, device, num_images_per_prompt
|
||||
)
|
||||
|
||||
if self.do_classifier_free_guidance:
|
||||
image_embeds = torch.cat([negative_image_embeds, image_embeds], dim=0)
|
||||
|
||||
# 4. Prepare timesteps
|
||||
timesteps, num_inference_steps = retrieve_timesteps(
|
||||
self.scheduler, num_inference_steps, device, timesteps
|
||||
)
|
||||
num_warmup_steps = max(
|
||||
len(timesteps) - num_inference_steps * self.scheduler.order, 0
|
||||
)
|
||||
self._num_timesteps = len(timesteps)
|
||||
|
||||
# 5. Prepare latent variables
|
||||
num_channels_latents = self.transformer.config.in_channels
|
||||
latents = self.prepare_latents(
|
||||
batch_size * num_images_per_prompt,
|
||||
num_tokens,
|
||||
num_channels_latents,
|
||||
image_embeds.dtype,
|
||||
device,
|
||||
generator,
|
||||
latents,
|
||||
)
|
||||
|
||||
# 6. Denoising loop
|
||||
self.set_progress_bar_config(
|
||||
desc="Denoising",
|
||||
ncols=125,
|
||||
disable=self._progress_bar_config['disable'] if hasattr(self, '_progress_bar_config') else False,
|
||||
)
|
||||
with self.progress_bar(total=len(timesteps)) as progress_bar:
|
||||
for i, t in enumerate(timesteps):
|
||||
if self.interrupt:
|
||||
continue
|
||||
|
||||
# expand the latents if we are doing classifier free guidance
|
||||
latent_model_input = (
|
||||
torch.cat([latents] * 2)
|
||||
if self.do_classifier_free_guidance
|
||||
else latents
|
||||
)
|
||||
# broadcast to batch dimension in a way that's compatible with ONNX/Core ML
|
||||
timestep = t.expand(latent_model_input.shape[0])
|
||||
|
||||
noise_pred = self.transformer(
|
||||
latent_model_input,
|
||||
timestep,
|
||||
encoder_hidden_states=image_embeds,
|
||||
attention_kwargs=attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0].to(dtype)
|
||||
|
||||
# perform guidance
|
||||
if self.do_classifier_free_guidance:
|
||||
noise_pred_uncond, noise_pred_image = noise_pred.chunk(2)
|
||||
noise_pred = noise_pred_uncond + self.guidance_scale * (
|
||||
noise_pred_image - noise_pred_uncond
|
||||
)
|
||||
|
||||
# compute the previous noisy sample x_t -> x_t-1
|
||||
latents_dtype = latents.dtype
|
||||
latents = self.scheduler.step(
|
||||
noise_pred, t, latents, return_dict=False
|
||||
)[0]
|
||||
|
||||
if latents.dtype != latents_dtype:
|
||||
if torch.backends.mps.is_available():
|
||||
# some platforms (eg. apple mps) misbehave due to a pytorch bug: https://github.com/pytorch/pytorch/pull/99272
|
||||
latents = latents.to(latents_dtype)
|
||||
|
||||
if callback_on_step_end is not None:
|
||||
callback_kwargs = {}
|
||||
for k in callback_on_step_end_tensor_inputs:
|
||||
callback_kwargs[k] = locals()[k]
|
||||
callback_outputs = callback_on_step_end(self, i, t, callback_kwargs)
|
||||
|
||||
latents = callback_outputs.pop("latents", latents)
|
||||
image_embeds_1 = callback_outputs.pop(
|
||||
"image_embeds_1", image_embeds_1
|
||||
)
|
||||
negative_image_embeds_1 = callback_outputs.pop(
|
||||
"negative_image_embeds_1", negative_image_embeds_1
|
||||
)
|
||||
image_embeds_2 = callback_outputs.pop(
|
||||
"image_embeds_2", image_embeds_2
|
||||
)
|
||||
negative_image_embeds_2 = callback_outputs.pop(
|
||||
"negative_image_embeds_2", negative_image_embeds_2
|
||||
)
|
||||
|
||||
# call the callback, if provided
|
||||
if i == len(timesteps) - 1 or (
|
||||
(i + 1) > num_warmup_steps and (i + 1) % self.scheduler.order == 0
|
||||
):
|
||||
progress_bar.update()
|
||||
|
||||
|
||||
# 7. decoder mesh
|
||||
self.vae.set_flash_decoder()
|
||||
output, meshes = [], []
|
||||
self.set_progress_bar_config(
|
||||
desc="Decoding",
|
||||
ncols=125,
|
||||
disable=self._progress_bar_config['disable'] if hasattr(self, '_progress_bar_config') else False,
|
||||
)
|
||||
with self.progress_bar(total=batch_size) as progress_bar:
|
||||
for i in range(batch_size):
|
||||
geometric_func = lambda x: self.vae.decode(latents[i].unsqueeze(0), sampled_points=x).sample
|
||||
try:
|
||||
mesh_v_f = hierarchical_extract_geometry(
|
||||
geometric_func,
|
||||
device,
|
||||
dtype=latents.dtype,
|
||||
bounds=bounds,
|
||||
dense_octree_depth=dense_octree_depth,
|
||||
hierarchical_octree_depth=hierarchical_octree_depth,
|
||||
max_num_expanded_coords=max_num_expanded_coords,
|
||||
# verbose=True
|
||||
)
|
||||
mesh = trimesh.Trimesh(mesh_v_f[0].astype(np.float32), mesh_v_f[1])
|
||||
except:
|
||||
mesh_v_f = None
|
||||
mesh = None
|
||||
output.append(mesh_v_f)
|
||||
meshes.append(mesh)
|
||||
progress_bar.update()
|
||||
|
||||
# Offload all models
|
||||
self.maybe_free_model_hooks()
|
||||
|
||||
if not return_dict:
|
||||
return (output, meshes)
|
||||
|
||||
return PartCrafterPipelineOutput(samples=output, meshes=meshes)
|
||||
|
||||
+17
@@ -0,0 +1,17 @@
|
||||
from dataclasses import dataclass
|
||||
from typing import List, Optional, Union
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import trimesh
|
||||
from diffusers.utils import BaseOutput
|
||||
|
||||
|
||||
@dataclass
|
||||
class PartCrafterPipelineOutput(BaseOutput):
|
||||
r"""
|
||||
Output class for ShapeDiff pipelines.
|
||||
"""
|
||||
|
||||
samples: torch.Tensor
|
||||
meshes: List[trimesh.Trimesh]
|
||||
@@ -0,0 +1,96 @@
|
||||
from diffusers.utils import logging
|
||||
|
||||
logger = logging.get_logger(__name__)
|
||||
|
||||
|
||||
class TransformerDiffusionMixin:
|
||||
r"""
|
||||
Helper for DiffusionPipeline with vae and transformer.(mainly for DIT)
|
||||
"""
|
||||
|
||||
def enable_vae_slicing(self):
|
||||
r"""
|
||||
Enable sliced VAE decoding. When this option is enabled, the VAE will split the input tensor in slices to
|
||||
compute decoding in several steps. This is useful to save some memory and allow larger batch sizes.
|
||||
"""
|
||||
self.vae.enable_slicing()
|
||||
|
||||
def disable_vae_slicing(self):
|
||||
r"""
|
||||
Disable sliced VAE decoding. If `enable_vae_slicing` was previously enabled, this method will go back to
|
||||
computing decoding in one step.
|
||||
"""
|
||||
self.vae.disable_slicing()
|
||||
|
||||
def enable_vae_tiling(self):
|
||||
r"""
|
||||
Enable tiled VAE decoding. When this option is enabled, the VAE will split the input tensor into tiles to
|
||||
compute decoding and encoding in several steps. This is useful for saving a large amount of memory and to allow
|
||||
processing larger images.
|
||||
"""
|
||||
self.vae.enable_tiling()
|
||||
|
||||
def disable_vae_tiling(self):
|
||||
r"""
|
||||
Disable tiled VAE decoding. If `enable_vae_tiling` was previously enabled, this method will go back to
|
||||
computing decoding in one step.
|
||||
"""
|
||||
self.vae.disable_tiling()
|
||||
|
||||
def fuse_qkv_projections(self, transformer: bool = True, vae: bool = True):
|
||||
"""
|
||||
Enables fused QKV projections. For self-attention modules, all projection matrices (i.e., query, key, value)
|
||||
are fused. For cross-attention modules, key and value projection matrices are fused.
|
||||
|
||||
<Tip warning={true}>
|
||||
|
||||
This API is 🧪 experimental.
|
||||
|
||||
</Tip>
|
||||
|
||||
Args:
|
||||
transformer (`bool`, defaults to `True`): To apply fusion on the Transformer.
|
||||
vae (`bool`, defaults to `True`): To apply fusion on the VAE.
|
||||
"""
|
||||
self.fusing_transformer = False
|
||||
self.fusing_vae = False
|
||||
|
||||
if transformer:
|
||||
self.fusing_transformer = True
|
||||
self.transformer.fuse_qkv_projections()
|
||||
|
||||
if vae:
|
||||
self.fusing_vae = True
|
||||
self.vae.fuse_qkv_projections()
|
||||
|
||||
def unfuse_qkv_projections(self, transformer: bool = True, vae: bool = True):
|
||||
"""Disable QKV projection fusion if enabled.
|
||||
|
||||
<Tip warning={true}>
|
||||
|
||||
This API is 🧪 experimental.
|
||||
|
||||
</Tip>
|
||||
|
||||
Args:
|
||||
transformer (`bool`, defaults to `True`): To apply fusion on the Transformer.
|
||||
vae (`bool`, defaults to `True`): To apply fusion on the VAE.
|
||||
|
||||
"""
|
||||
if transformer:
|
||||
if not self.fusing_transformer:
|
||||
logger.warning(
|
||||
"The UNet was not initially fused for QKV projections. Doing nothing."
|
||||
)
|
||||
else:
|
||||
self.transformer.unfuse_qkv_projections()
|
||||
self.fusing_transformer = False
|
||||
|
||||
if vae:
|
||||
if not self.fusing_vae:
|
||||
logger.warning(
|
||||
"The VAE was not initially fused for QKV projections. Doing nothing."
|
||||
)
|
||||
else:
|
||||
self.vae.unfuse_qkv_projections()
|
||||
self.fusing_vae = False
|
||||
@@ -0,0 +1,5 @@
|
||||
from .scheduling_rectified_flow import (
|
||||
RectifiedFlowScheduler,
|
||||
compute_density_for_timestep_sampling,
|
||||
compute_loss_weighting,
|
||||
)
|
||||
+327
@@ -0,0 +1,327 @@
|
||||
"""
|
||||
Adapted from https://github.com/huggingface/diffusers/blob/v0.30.3/src/diffusers/schedulers/scheduling_flow_match_euler_discrete.py.
|
||||
"""
|
||||
|
||||
import math
|
||||
from dataclasses import dataclass
|
||||
from typing import List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers.configuration_utils import ConfigMixin, register_to_config
|
||||
from diffusers.schedulers.scheduling_utils import SchedulerMixin
|
||||
from diffusers.utils import BaseOutput, logging
|
||||
from torch.distributions import LogisticNormal
|
||||
|
||||
logger = logging.get_logger(__name__) # pylint: disable=invalid-name
|
||||
|
||||
|
||||
# TODO: may move to training_utils.py
|
||||
def compute_density_for_timestep_sampling(
|
||||
weighting_scheme: str,
|
||||
batch_size: int,
|
||||
logit_mean: float = 0.0,
|
||||
logit_std: float = 1.0,
|
||||
mode_scale: float = None,
|
||||
):
|
||||
if weighting_scheme == "logit_normal":
|
||||
# See 3.1 in the SD3 paper ($rf/lognorm(0.00,1.00)$).
|
||||
u = torch.normal(
|
||||
mean=logit_mean, std=logit_std, size=(batch_size,), device="cpu"
|
||||
)
|
||||
u = torch.nn.functional.sigmoid(u)
|
||||
elif weighting_scheme == "logit_normal_dist":
|
||||
u = (
|
||||
LogisticNormal(loc=logit_mean, scale=logit_std)
|
||||
.sample((batch_size,))[:, 0]
|
||||
.to("cpu")
|
||||
)
|
||||
elif weighting_scheme == "mode":
|
||||
u = torch.rand(size=(batch_size,), device="cpu")
|
||||
u = 1 - u - mode_scale * (torch.cos(math.pi * u / 2) ** 2 - 1 + u)
|
||||
else:
|
||||
u = torch.rand(size=(batch_size,), device="cpu")
|
||||
return u
|
||||
|
||||
|
||||
def compute_loss_weighting(weighting_scheme: str, sigmas=None):
|
||||
"""
|
||||
Computes loss weighting scheme for SD3 training.
|
||||
|
||||
Courtesy: This was contributed by Rafie Walker in https://github.com/huggingface/diffusers/pull/8528.
|
||||
|
||||
SD3 paper reference: https://arxiv.org/abs/2403.03206v1.
|
||||
"""
|
||||
if weighting_scheme == "sigma_sqrt":
|
||||
weighting = (sigmas**-2.0).float()
|
||||
elif weighting_scheme == "cosmap":
|
||||
bot = 1 - 2 * sigmas + 2 * sigmas**2
|
||||
weighting = 2 / (math.pi * bot)
|
||||
else:
|
||||
weighting = torch.ones_like(sigmas)
|
||||
return weighting
|
||||
|
||||
|
||||
@dataclass
|
||||
class RectifiedFlowSchedulerOutput(BaseOutput):
|
||||
"""
|
||||
Output class for the scheduler's `step` function output.
|
||||
|
||||
Args:
|
||||
prev_sample (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)` for images):
|
||||
Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the
|
||||
denoising loop.
|
||||
"""
|
||||
|
||||
prev_sample: torch.FloatTensor
|
||||
|
||||
|
||||
class RectifiedFlowScheduler(SchedulerMixin, ConfigMixin):
|
||||
"""
|
||||
The rectified flow scheduler is a scheduler that is used to propagate the diffusion process in the rectified flow.
|
||||
|
||||
This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic
|
||||
methods the library implements for all schedulers such as loading and saving.
|
||||
|
||||
Args:
|
||||
num_train_timesteps (`int`, defaults to 1000):
|
||||
The number of diffusion steps to train the model.
|
||||
timestep_spacing (`str`, defaults to `"linspace"`):
|
||||
The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and
|
||||
Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information.
|
||||
shift (`float`, defaults to 1.0):
|
||||
The shift value for the timestep schedule.
|
||||
"""
|
||||
|
||||
_compatibles = []
|
||||
order = 1
|
||||
|
||||
@register_to_config
|
||||
def __init__(
|
||||
self,
|
||||
num_train_timesteps: int = 1000,
|
||||
shift: float = 1.0,
|
||||
use_dynamic_shifting: bool = False,
|
||||
):
|
||||
# pre-compute timesteps and sigmas; no use in fact
|
||||
# NOTE that shape diffusion sample timesteps randomly or in a distribution,
|
||||
# instead of sampling from the pre-defined linspace
|
||||
timesteps = np.array(
|
||||
[
|
||||
(1.0 - i / num_train_timesteps) * num_train_timesteps
|
||||
for i in range(num_train_timesteps)
|
||||
]
|
||||
)
|
||||
timesteps = torch.from_numpy(timesteps).to(dtype=torch.float32)
|
||||
|
||||
sigmas = timesteps / num_train_timesteps
|
||||
if not use_dynamic_shifting:
|
||||
# when use_dynamic_shifting is True, we apply the timestep shifting on the fly based on the image resolution
|
||||
sigmas = self.time_shift(sigmas)
|
||||
|
||||
self.timesteps = sigmas * num_train_timesteps
|
||||
|
||||
self._step_index = None
|
||||
self._begin_index = None
|
||||
|
||||
self.sigmas = sigmas.to("cpu") # to avoid too much CPU/GPU communication
|
||||
|
||||
@property
|
||||
def step_index(self):
|
||||
"""
|
||||
The index counter for current timestep. It will increase 1 after each scheduler step.
|
||||
"""
|
||||
return self._step_index
|
||||
|
||||
@property
|
||||
def begin_index(self):
|
||||
"""
|
||||
The index for the first timestep. It should be set from pipeline with `set_begin_index` method.
|
||||
"""
|
||||
return self._begin_index
|
||||
|
||||
# Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index
|
||||
def set_begin_index(self, begin_index: int = 0):
|
||||
"""
|
||||
Sets the begin index for the scheduler. This function should be run from pipeline before the inference.
|
||||
|
||||
Args:
|
||||
begin_index (`int`):
|
||||
The begin index for the scheduler.
|
||||
"""
|
||||
self._begin_index = begin_index
|
||||
|
||||
def _sigma_to_t(self, sigma):
|
||||
return sigma * self.config.num_train_timesteps
|
||||
|
||||
def _t_to_sigma(self, timestep):
|
||||
return timestep / self.config.num_train_timesteps
|
||||
|
||||
def time_shift_dynamic(self, mu: float, sigma: float, t: torch.Tensor):
|
||||
return math.exp(mu) / (math.exp(mu) + (1 / t - 1) ** sigma)
|
||||
|
||||
def time_shift(self, t: torch.Tensor):
|
||||
return self.config.shift * t / (1 + (self.config.shift - 1) * t)
|
||||
|
||||
def set_timesteps(
|
||||
self,
|
||||
num_inference_steps: int = None,
|
||||
device: Union[str, torch.device] = None,
|
||||
sigmas: Optional[List[float]] = None,
|
||||
mu: Optional[float] = None,
|
||||
):
|
||||
"""
|
||||
Sets the discrete timesteps used for the diffusion chain (to be run before inference).
|
||||
|
||||
Args:
|
||||
num_inference_steps (`int`):
|
||||
The number of diffusion steps used when generating samples with a pre-trained model.
|
||||
device (`str` or `torch.device`, *optional*):
|
||||
The device to which the timesteps should be moved to. If `None`, the timesteps are not moved.
|
||||
"""
|
||||
|
||||
if self.config.use_dynamic_shifting and mu is None:
|
||||
raise ValueError(
|
||||
" you have to pass a value for `mu` when `use_dynamic_shifting` is set to be `True`"
|
||||
)
|
||||
|
||||
if sigmas is None:
|
||||
self.num_inference_steps = num_inference_steps
|
||||
timesteps = np.array(
|
||||
[
|
||||
(1.0 - i / num_inference_steps) * self.config.num_train_timesteps
|
||||
for i in range(num_inference_steps)
|
||||
]
|
||||
) # different from the original code in SD3
|
||||
sigmas = timesteps / self.config.num_train_timesteps
|
||||
|
||||
if self.config.use_dynamic_shifting:
|
||||
sigmas = self.time_shift_dynamic(mu, 1.0, sigmas)
|
||||
else:
|
||||
sigmas = self.config.shift * sigmas / (1 + (self.config.shift - 1) * sigmas)
|
||||
|
||||
sigmas = torch.from_numpy(sigmas).to(dtype=torch.float32, device=device)
|
||||
timesteps = sigmas * self.config.num_train_timesteps
|
||||
|
||||
self.timesteps = timesteps.to(device=device)
|
||||
self.sigmas = torch.cat([sigmas, torch.zeros(1, device=sigmas.device)])
|
||||
|
||||
self._step_index = None
|
||||
self._begin_index = None
|
||||
|
||||
def index_for_timestep(self, timestep, schedule_timesteps=None):
|
||||
if schedule_timesteps is None:
|
||||
schedule_timesteps = self.timesteps
|
||||
|
||||
indices = (schedule_timesteps == timestep).nonzero()
|
||||
|
||||
# The sigma index that is taken for the **very** first `step`
|
||||
# is always the second index (or the last index if there is only 1)
|
||||
# This way we can ensure we don't accidentally skip a sigma in
|
||||
# case we start in the middle of the denoising schedule (e.g. for image-to-image)
|
||||
pos = 1 if len(indices) > 1 else 0
|
||||
|
||||
return indices[pos].item()
|
||||
|
||||
def _init_step_index(self, timestep):
|
||||
if self.begin_index is None:
|
||||
if isinstance(timestep, torch.Tensor):
|
||||
timestep = timestep.to(self.timesteps.device)
|
||||
self._step_index = self.index_for_timestep(timestep)
|
||||
else:
|
||||
self._step_index = self._begin_index
|
||||
|
||||
def step(
|
||||
self,
|
||||
model_output: torch.FloatTensor,
|
||||
timestep: Union[float, torch.FloatTensor],
|
||||
sample: torch.FloatTensor,
|
||||
s_churn: float = 0.0,
|
||||
s_tmin: float = 0.0,
|
||||
s_tmax: float = float("inf"),
|
||||
s_noise: float = 1.0,
|
||||
generator: Optional[torch.Generator] = None,
|
||||
return_dict: bool = True,
|
||||
) -> Union[RectifiedFlowSchedulerOutput, Tuple]:
|
||||
"""
|
||||
Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion
|
||||
process from the learned model outputs (most often the predicted noise).
|
||||
|
||||
Args:
|
||||
model_output (`torch.FloatTensor`):
|
||||
The direct output from learned diffusion model.
|
||||
timestep (`float`):
|
||||
The current discrete timestep in the diffusion chain.
|
||||
sample (`torch.FloatTensor`):
|
||||
A current instance of a sample created by the diffusion process.
|
||||
s_churn (`float`):
|
||||
s_tmin (`float`):
|
||||
s_tmax (`float`):
|
||||
s_noise (`float`, defaults to 1.0):
|
||||
Scaling factor for noise added to the sample.
|
||||
generator (`torch.Generator`, *optional*):
|
||||
A random number generator.
|
||||
return_dict (`bool`):
|
||||
Whether or not to return a [`~schedulers.scheduling_euler_discrete.EulerDiscreteSchedulerOutput`] or
|
||||
tuple.
|
||||
|
||||
Returns:
|
||||
[`~schedulers.scheduling_euler_discrete.EulerDiscreteSchedulerOutput`] or `tuple`:
|
||||
If return_dict is `True`, [`~schedulers.scheduling_euler_discrete.EulerDiscreteSchedulerOutput`] is
|
||||
returned, otherwise a tuple is returned where the first element is the sample tensor.
|
||||
"""
|
||||
|
||||
if (
|
||||
isinstance(timestep, int)
|
||||
or isinstance(timestep, torch.IntTensor)
|
||||
or isinstance(timestep, torch.LongTensor)
|
||||
):
|
||||
raise ValueError(
|
||||
(
|
||||
"Passing integer indices (e.g. from `enumerate(timesteps)`) as timesteps to"
|
||||
" `EulerDiscreteScheduler.step()` is not supported. Make sure to pass"
|
||||
" one of the `scheduler.timesteps` as a timestep."
|
||||
),
|
||||
)
|
||||
|
||||
if self.step_index is None:
|
||||
self._init_step_index(timestep)
|
||||
|
||||
# Upcast to avoid precision issues when computing prev_sample
|
||||
sample = sample.to(torch.float32)
|
||||
|
||||
sigma = self.sigmas[self.step_index]
|
||||
sigma_next = self.sigmas[self.step_index + 1]
|
||||
|
||||
# Here different directions are used for the flow matching
|
||||
prev_sample = sample + (sigma - sigma_next) * model_output
|
||||
|
||||
# Cast sample back to model compatible dtype
|
||||
prev_sample = prev_sample.to(model_output.dtype)
|
||||
|
||||
# upon completion increase step index by one
|
||||
self._step_index += 1
|
||||
|
||||
if not return_dict:
|
||||
return (prev_sample,)
|
||||
|
||||
return RectifiedFlowSchedulerOutput(prev_sample=prev_sample)
|
||||
|
||||
def scale_noise(
|
||||
self,
|
||||
original_samples: torch.Tensor,
|
||||
noise: torch.Tensor,
|
||||
timesteps: torch.IntTensor,
|
||||
) -> torch.Tensor:
|
||||
"""
|
||||
Forward function for the noise scaling in the flow matching.
|
||||
"""
|
||||
sigmas = self._t_to_sigma(timesteps.to(dtype=torch.float32))
|
||||
|
||||
while len(sigmas.shape) < len(original_samples.shape):
|
||||
sigmas = sigmas.unsqueeze(-1)
|
||||
|
||||
return (1.0 - sigmas) * original_samples + sigmas * noise
|
||||
|
||||
def __len__(self):
|
||||
return self.config.num_train_timesteps
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,191 @@
|
||||
from partcrafter_src.utils.typing_utils import *
|
||||
|
||||
import os
|
||||
import numpy as np
|
||||
import trimesh
|
||||
import torch
|
||||
|
||||
def normalize_mesh(
|
||||
mesh: Union[trimesh.Trimesh, trimesh.Scene],
|
||||
scale: float = 2.0,
|
||||
):
|
||||
# if not isinstance(mesh, trimesh.Trimesh) and not isinstance(mesh, trimesh.Scene):
|
||||
# raise ValueError("Input mesh is not a trimesh.Trimesh or trimesh.Scene object.")
|
||||
bbox = mesh.bounding_box
|
||||
translation = -bbox.centroid
|
||||
scale = scale / bbox.primitive.extents.max()
|
||||
mesh.apply_translation(translation)
|
||||
mesh.apply_scale(scale)
|
||||
return mesh
|
||||
|
||||
def remove_overlapping_vertices(mesh: trimesh.Trimesh, reserve_material: bool = False):
|
||||
if not isinstance(mesh, trimesh.Trimesh):
|
||||
raise ValueError("Input mesh is not a trimesh.Trimesh object.")
|
||||
vertices = mesh.vertices
|
||||
faces = mesh.faces
|
||||
unique_vertices, index_map, inverse_map = np.unique(
|
||||
vertices, axis=0, return_index=True, return_inverse=True
|
||||
)
|
||||
clean_faces = inverse_map[faces]
|
||||
clean_mesh = trimesh.Trimesh(vertices=unique_vertices, faces=clean_faces, process=True)
|
||||
if reserve_material:
|
||||
uv = mesh.visual.uv
|
||||
material = mesh.visual.material
|
||||
clean_uv = uv[index_map]
|
||||
clean_visual = trimesh.visual.TextureVisuals(uv=clean_uv, material=material)
|
||||
clean_mesh.visual = clean_visual
|
||||
return clean_mesh
|
||||
|
||||
RGB = [
|
||||
(82, 170, 220),
|
||||
(215, 91, 78),
|
||||
(45, 136, 117),
|
||||
(247, 172, 83),
|
||||
(124, 121, 121),
|
||||
(127, 171, 209),
|
||||
(243, 152, 101),
|
||||
(145, 204, 192),
|
||||
(150, 59, 121),
|
||||
(181, 206, 78),
|
||||
(189, 119, 149),
|
||||
(199, 193, 222),
|
||||
(200, 151, 54),
|
||||
(236, 110, 102),
|
||||
(238, 182, 212),
|
||||
]
|
||||
|
||||
|
||||
def get_colored_mesh_composition(
|
||||
meshes: Union[List[trimesh.Trimesh], trimesh.Scene],
|
||||
is_random: bool = True,
|
||||
is_sorted: bool = False,
|
||||
RGB: List[Tuple] = RGB
|
||||
):
|
||||
if isinstance(meshes, trimesh.Scene):
|
||||
meshes = meshes.dump()
|
||||
if is_sorted:
|
||||
volumes = []
|
||||
for mesh in meshes:
|
||||
try:
|
||||
volume = mesh.volume
|
||||
except:
|
||||
volume = 0.0
|
||||
volumes.append(volume)
|
||||
# sort by volume from large to small
|
||||
meshes = [x for _, x in sorted(zip(volumes, meshes), key=lambda pair: pair[0], reverse=True)]
|
||||
colored_scene = trimesh.Scene()
|
||||
for idx, mesh in enumerate(meshes):
|
||||
if is_random:
|
||||
color = (np.random.rand(3) * 256).astype(int)
|
||||
else:
|
||||
color = np.array(RGB[idx % len(RGB)])
|
||||
mesh.visual = trimesh.visual.ColorVisuals(
|
||||
mesh=mesh,
|
||||
vertex_colors=color,
|
||||
)
|
||||
colored_scene.add_geometry(mesh)
|
||||
return colored_scene
|
||||
|
||||
def mesh_to_surface(
|
||||
mesh: trimesh.Trimesh,
|
||||
num_pc: int = 204800,
|
||||
clip_to_num_vertices: bool = False,
|
||||
return_dict: bool = False,
|
||||
):
|
||||
# if not isinstance(mesh, trimesh.Trimesh):
|
||||
# raise ValueError("mesh must be a trimesh.Trimesh object")
|
||||
if clip_to_num_vertices:
|
||||
num_pc = min(num_pc, mesh.vertices.shape[0])
|
||||
points, face_indices = mesh.sample(num_pc, return_index=True)
|
||||
normals = mesh.face_normals[face_indices]
|
||||
if return_dict:
|
||||
return {
|
||||
"surface_points": points,
|
||||
"surface_normals": normals,
|
||||
}
|
||||
return points, normals
|
||||
|
||||
def scene_to_parts(
|
||||
mesh: trimesh.Scene,
|
||||
normalize: bool = True,
|
||||
scale: float = 2.0,
|
||||
num_part_pc: int = 204800,
|
||||
clip_to_num_part_vertices: bool = False,
|
||||
return_type: Literal["mesh", "point"] = "mesh",
|
||||
) -> Union[List[trimesh.Geometry], List[Dict[str, np.ndarray]]]:
|
||||
if not isinstance(mesh, trimesh.Scene):
|
||||
raise ValueError("mesh must be a trimesh.Scene object")
|
||||
if normalize:
|
||||
mesh = normalize_mesh(mesh, scale=scale)
|
||||
parts: List[trimesh.Geometry] = mesh.dump()
|
||||
if return_type == "point":
|
||||
datas: List[Dict[str, np.ndarray]] = []
|
||||
for geom in parts:
|
||||
data = mesh_to_surface(
|
||||
geom,
|
||||
num_pc=num_part_pc,
|
||||
clip_to_num_vertices=clip_to_num_part_vertices,
|
||||
return_dict=True,
|
||||
)
|
||||
datas.append(data)
|
||||
return datas
|
||||
elif return_type == "mesh":
|
||||
return parts
|
||||
else:
|
||||
raise ValueError("return_type must be 'mesh' or 'point'")
|
||||
|
||||
def get_center(mesh: trimesh.Trimesh, method: Literal['mass', 'bbox']):
|
||||
if method == 'mass':
|
||||
return mesh.center_mass
|
||||
elif method =='bbox':
|
||||
return mesh.bounding_box.centroid
|
||||
else:
|
||||
raise ValueError('type must be mass or bbox')
|
||||
|
||||
def get_direction(vector: np.ndarray):
|
||||
return vector / np.linalg.norm(vector)
|
||||
|
||||
def move_mesh_by_center(mesh: trimesh.Trimesh, scale: float, method: Literal['mass', 'bbox'] = 'mass'):
|
||||
offset = scale - 1
|
||||
center = get_center(mesh, method)
|
||||
direction = get_direction(center)
|
||||
translation = direction * offset
|
||||
mesh = mesh.copy()
|
||||
mesh.apply_translation(translation)
|
||||
return mesh
|
||||
|
||||
def move_meshes_by_center(meshes: Union[List[trimesh.Trimesh], trimesh.Scene], scale: float):
|
||||
if isinstance(meshes, trimesh.Scene):
|
||||
meshes = meshes.dump()
|
||||
moved_meshes = []
|
||||
for mesh in meshes:
|
||||
moved_mesh = move_mesh_by_center(mesh, scale)
|
||||
moved_meshes.append(moved_mesh)
|
||||
moved_meshes = trimesh.Scene(moved_meshes)
|
||||
return moved_meshes
|
||||
|
||||
def get_series_splited_meshes(meshes: List[trimesh.Trimesh], scale: float, num_steps: int) -> List[trimesh.Scene]:
|
||||
series_meshes = []
|
||||
for i in range(num_steps):
|
||||
temp_scale = 1 + (scale - 1) * i / (num_steps - 1)
|
||||
temp_meshes = move_meshes_by_center(meshes, temp_scale)
|
||||
series_meshes.append(temp_meshes)
|
||||
return series_meshes
|
||||
|
||||
def load_surface(data, num_pc=204800):
|
||||
|
||||
surface = data["surface_points"] # Nx3
|
||||
normal = data["surface_normals"] # Nx3
|
||||
|
||||
rng = np.random.default_rng()
|
||||
ind = rng.choice(surface.shape[0], num_pc, replace=False)
|
||||
surface = torch.FloatTensor(surface[ind])
|
||||
normal = torch.FloatTensor(normal[ind])
|
||||
surface = torch.cat([surface, normal], dim=-1)
|
||||
|
||||
return surface
|
||||
|
||||
def load_surfaces(surfaces, num_pc=204800):
|
||||
surfaces = [load_surface(surface, num_pc) for surface in surfaces]
|
||||
surfaces = torch.stack(surfaces, dim=0)
|
||||
return surfaces
|
||||
@@ -0,0 +1,151 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
import os
|
||||
from skimage.morphology import remove_small_objects
|
||||
from skimage.measure import label
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
import cv2
|
||||
from torchvision import transforms
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
import torchvision.transforms.functional as TF
|
||||
|
||||
def find_bounding_box(gray_image):
|
||||
_, binary_image = cv2.threshold(gray_image, 1, 255, cv2.THRESH_BINARY)
|
||||
contours, _ = cv2.findContours(binary_image, cv2.RETR_EXTERNAL, cv2.CHAIN_APPROX_SIMPLE)
|
||||
max_contour = max(contours, key=cv2.contourArea)
|
||||
x, y, w, h = cv2.boundingRect(max_contour)
|
||||
return x, y, w, h
|
||||
|
||||
def load_image(img_path, bg_color=None, rmbg_net=None, padding_ratio=0.1, device='cuda'):
|
||||
img = cv2.imread(img_path, cv2.IMREAD_UNCHANGED)
|
||||
if img is None:
|
||||
return f"invalid image path {img_path}"
|
||||
|
||||
def is_valid_alpha(alpha, min_ratio = 0.01):
|
||||
bins = 20
|
||||
if isinstance(alpha, np.ndarray):
|
||||
hist = cv2.calcHist([alpha], [0], None, [bins], [0, 256])
|
||||
else:
|
||||
hist = torch.histc(alpha, bins=bins, min=0, max=1)
|
||||
min_hist_val = alpha.shape[0] * alpha.shape[1] * min_ratio
|
||||
return hist[0] >= min_hist_val and hist[-1] >= min_hist_val
|
||||
|
||||
def rmbg(image: torch.Tensor) -> torch.Tensor:
|
||||
image = TF.normalize(image, [0.5,0.5,0.5], [1.0,1.0,1.0]).unsqueeze(0)
|
||||
result=rmbg_net(image)
|
||||
return result[0][0]
|
||||
|
||||
if len(img.shape) == 2:
|
||||
num_channels = 1
|
||||
else:
|
||||
num_channels = img.shape[2]
|
||||
|
||||
# check if too large
|
||||
height, width = img.shape[:2]
|
||||
if height > width:
|
||||
scale = 2000 / height
|
||||
else:
|
||||
scale = 2000 / width
|
||||
if scale < 1:
|
||||
new_size = (int(width * scale), int(height * scale))
|
||||
img = cv2.resize(img, new_size, interpolation=cv2.INTER_AREA)
|
||||
|
||||
if img.dtype != 'uint8':
|
||||
img = (img * (255. / np.iinfo(img.dtype).max)).astype(np.uint8)
|
||||
|
||||
rgb_image = None
|
||||
alpha = None
|
||||
|
||||
if num_channels == 1:
|
||||
rgb_image = cv2.cvtColor(img, cv2.COLOR_GRAY2RGB)
|
||||
elif num_channels == 3:
|
||||
rgb_image = cv2.cvtColor(img, cv2.COLOR_BGR2RGB)
|
||||
elif num_channels == 4:
|
||||
rgb_image = cv2.cvtColor(img, cv2.COLOR_BGRA2RGB)
|
||||
|
||||
b, g, r, alpha = cv2.split(img)
|
||||
if not is_valid_alpha(alpha):
|
||||
alpha = None
|
||||
else:
|
||||
alpha_gpu = torch.from_numpy(alpha).unsqueeze(0).to(device).float() / 255.
|
||||
else:
|
||||
return f"invalid image: channels {num_channels}"
|
||||
|
||||
rgb_image_gpu = torch.from_numpy(rgb_image).to(device).float().permute(2, 0, 1) / 255.
|
||||
if alpha is None:
|
||||
resize_transform = transforms.Resize((384, 384), antialias=True)
|
||||
rgb_image_resized = resize_transform(rgb_image_gpu)
|
||||
normalize_image = rgb_image_resized * 2 - 1
|
||||
|
||||
mean_color = torch.tensor([0.485, 0.456, 0.406]).view(3, 1, 1).to(device)
|
||||
resize_transform = transforms.Resize((1024, 1024), antialias=True)
|
||||
rgb_image_resized = resize_transform(rgb_image_gpu)
|
||||
max_value = rgb_image_resized.flatten().max()
|
||||
if max_value < 1e-3:
|
||||
return "invalid image: pure black image"
|
||||
normalize_image = rgb_image_resized / max_value - mean_color
|
||||
normalize_image = normalize_image.unsqueeze(0)
|
||||
resize_transform = transforms.Resize((rgb_image_gpu.shape[1], rgb_image_gpu.shape[2]), antialias=True)
|
||||
|
||||
# seg from rmbg
|
||||
alpha_gpu_rmbg = rmbg(rgb_image_resized)
|
||||
alpha_gpu_rmbg = alpha_gpu_rmbg.squeeze(0)
|
||||
alpha_gpu_rmbg = resize_transform(alpha_gpu_rmbg)
|
||||
ma, mi = alpha_gpu_rmbg.max(), alpha_gpu_rmbg.min()
|
||||
alpha_gpu_rmbg = (alpha_gpu_rmbg - mi) / (ma - mi)
|
||||
|
||||
alpha_gpu = alpha_gpu_rmbg
|
||||
|
||||
alpha_gpu_tmp = alpha_gpu * 255
|
||||
alpha = alpha_gpu_tmp.to(torch.uint8).squeeze().cpu().numpy()
|
||||
|
||||
_, alpha = cv2.threshold(alpha, 0, 255, cv2.THRESH_BINARY+cv2.THRESH_OTSU)
|
||||
labeled_alpha = label(alpha)
|
||||
cleaned_alpha = remove_small_objects(labeled_alpha, min_size=200)
|
||||
cleaned_alpha = (cleaned_alpha > 0).astype(np.uint8)
|
||||
alpha = cleaned_alpha * 255
|
||||
alpha_gpu = torch.from_numpy(cleaned_alpha).to(device).float().unsqueeze(0)
|
||||
x, y, w, h = find_bounding_box(alpha)
|
||||
|
||||
# If alpha is provided, the bounds of all foreground are used
|
||||
else:
|
||||
rows, cols = np.where(alpha > 0)
|
||||
if rows.size > 0 and cols.size > 0:
|
||||
x_min = np.min(cols)
|
||||
y_min = np.min(rows)
|
||||
x_max = np.max(cols)
|
||||
y_max = np.max(rows)
|
||||
|
||||
width = x_max - x_min + 1
|
||||
height = y_max - y_min + 1
|
||||
x, y, w, h = x_min, y_min, width, height
|
||||
|
||||
if np.all(alpha==0):
|
||||
raise ValueError(f"input image too small")
|
||||
|
||||
bg_gray = bg_color[0]
|
||||
bg_color = torch.from_numpy(bg_color).float().to(device).repeat(alpha_gpu.shape[1], alpha_gpu.shape[2], 1).permute(2, 0, 1)
|
||||
rgb_image_gpu = rgb_image_gpu * alpha_gpu + bg_color * (1 - alpha_gpu)
|
||||
padding_size = [0] * 6
|
||||
if w > h:
|
||||
padding_size[0] = int(w * padding_ratio)
|
||||
padding_size[2] = int(padding_size[0] + (w - h) / 2)
|
||||
else:
|
||||
padding_size[2] = int(h * padding_ratio)
|
||||
padding_size[0] = int(padding_size[2] + (h - w) / 2)
|
||||
padding_size[1] = padding_size[0]
|
||||
padding_size[3] = padding_size[2]
|
||||
padded_tensor = F.pad(rgb_image_gpu[:, y:(y+h), x:(x+w)], pad=tuple(padding_size), mode='constant', value=bg_gray)
|
||||
|
||||
return padded_tensor
|
||||
|
||||
def prepare_image(image_path, bg_color=np.array([1.0, 1.0, 1.0]), rmbg_net=None, padding_ratio=0.1, device='cuda'):
|
||||
if os.path.isfile(image_path):
|
||||
img_tensor = load_image(image_path, bg_color=bg_color, rmbg_net=rmbg_net, padding_ratio=padding_ratio, device=device)
|
||||
img_np = img_tensor.permute(1,2,0).cpu().numpy()
|
||||
img_pil = Image.fromarray((img_np*255).astype(np.uint8))
|
||||
|
||||
return img_pil
|
||||
else:
|
||||
raise ValueError(f"Invalid image path: {image_path}")
|
||||
@@ -0,0 +1,228 @@
|
||||
from partcrafter_src.utils.typing_utils import *
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import scipy.ndimage
|
||||
from skimage import measure
|
||||
from einops import repeat
|
||||
import torch.nn.functional as F
|
||||
|
||||
def generate_dense_grid_points(
|
||||
bbox_min: np.ndarray, bbox_max: np.ndarray, octree_depth: int, indexing: str = "ij"
|
||||
):
|
||||
length = bbox_max - bbox_min
|
||||
num_cells = np.exp2(octree_depth)
|
||||
x = np.linspace(bbox_min[0], bbox_max[0], int(num_cells) + 1, dtype=np.float32)
|
||||
y = np.linspace(bbox_min[1], bbox_max[1], int(num_cells) + 1, dtype=np.float32)
|
||||
z = np.linspace(bbox_min[2], bbox_max[2], int(num_cells) + 1, dtype=np.float32)
|
||||
[xs, ys, zs] = np.meshgrid(x, y, z, indexing=indexing)
|
||||
xyz = np.stack((xs, ys, zs), axis=-1)
|
||||
xyz = xyz.reshape(-1, 3)
|
||||
grid_size = [int(num_cells) + 1, int(num_cells) + 1, int(num_cells) + 1]
|
||||
|
||||
return xyz, grid_size, length
|
||||
|
||||
def generate_dense_grid_points_gpu(
|
||||
bbox_min: torch.Tensor,
|
||||
bbox_max: torch.Tensor,
|
||||
octree_depth: int,
|
||||
indexing: str = "ij",
|
||||
dtype: torch.dtype = torch.float16
|
||||
):
|
||||
length = bbox_max - bbox_min
|
||||
num_cells = 2 ** octree_depth
|
||||
device = bbox_min.device
|
||||
|
||||
x = torch.linspace(bbox_min[0], bbox_max[0], int(num_cells), dtype=dtype, device=device)
|
||||
y = torch.linspace(bbox_min[1], bbox_max[1], int(num_cells), dtype=dtype, device=device)
|
||||
z = torch.linspace(bbox_min[2], bbox_max[2], int(num_cells), dtype=dtype, device=device)
|
||||
|
||||
xs, ys, zs = torch.meshgrid(x, y, z, indexing=indexing)
|
||||
xyz = torch.stack((xs, ys, zs), dim=-1)
|
||||
xyz = xyz.view(-1, 3)
|
||||
grid_size = [int(num_cells), int(num_cells), int(num_cells)]
|
||||
|
||||
return xyz, grid_size, length
|
||||
|
||||
def find_mesh_grid_coordinates_fast_gpu(
|
||||
occupancy_grid,
|
||||
n_limits=-1
|
||||
):
|
||||
core_grid = occupancy_grid[1:-1, 1:-1, 1:-1]
|
||||
occupied = core_grid > 0
|
||||
|
||||
neighbors_unoccupied = (
|
||||
(occupancy_grid[:-2, :-2, :-2] < 0)
|
||||
| (occupancy_grid[:-2, :-2, 1:-1] < 0)
|
||||
| (occupancy_grid[:-2, :-2, 2:] < 0) # x-1, y-1, z-1/0/1
|
||||
| (occupancy_grid[:-2, 1:-1, :-2] < 0)
|
||||
| (occupancy_grid[:-2, 1:-1, 1:-1] < 0)
|
||||
| (occupancy_grid[:-2, 1:-1, 2:] < 0) # x-1, y0, z-1/0/1
|
||||
| (occupancy_grid[:-2, 2:, :-2] < 0)
|
||||
| (occupancy_grid[:-2, 2:, 1:-1] < 0)
|
||||
| (occupancy_grid[:-2, 2:, 2:] < 0) # x-1, y+1, z-1/0/1
|
||||
| (occupancy_grid[1:-1, :-2, :-2] < 0)
|
||||
| (occupancy_grid[1:-1, :-2, 1:-1] < 0)
|
||||
| (occupancy_grid[1:-1, :-2, 2:] < 0) # x0, y-1, z-1/0/1
|
||||
| (occupancy_grid[1:-1, 1:-1, :-2] < 0)
|
||||
| (occupancy_grid[1:-1, 1:-1, 2:] < 0) # x0, y0, z-1/1
|
||||
| (occupancy_grid[1:-1, 2:, :-2] < 0)
|
||||
| (occupancy_grid[1:-1, 2:, 1:-1] < 0)
|
||||
| (occupancy_grid[1:-1, 2:, 2:] < 0) # x0, y+1, z-1/0/1
|
||||
| (occupancy_grid[2:, :-2, :-2] < 0)
|
||||
| (occupancy_grid[2:, :-2, 1:-1] < 0)
|
||||
| (occupancy_grid[2:, :-2, 2:] < 0) # x+1, y-1, z-1/0/1
|
||||
| (occupancy_grid[2:, 1:-1, :-2] < 0)
|
||||
| (occupancy_grid[2:, 1:-1, 1:-1] < 0)
|
||||
| (occupancy_grid[2:, 1:-1, 2:] < 0) # x+1, y0, z-1/0/1
|
||||
| (occupancy_grid[2:, 2:, :-2] < 0)
|
||||
| (occupancy_grid[2:, 2:, 1:-1] < 0)
|
||||
| (occupancy_grid[2:, 2:, 2:] < 0) # x+1, y+1, z-1/0/1
|
||||
)
|
||||
core_mesh_coords = torch.nonzero(occupied & neighbors_unoccupied, as_tuple=False) + 1
|
||||
|
||||
if n_limits != -1 and core_mesh_coords.shape[0] > n_limits:
|
||||
print(f"core mesh coords {core_mesh_coords.shape[0]} is too large, limited to {n_limits}")
|
||||
ind = np.random.choice(core_mesh_coords.shape[0], n_limits, True)
|
||||
core_mesh_coords = core_mesh_coords[ind]
|
||||
|
||||
return core_mesh_coords
|
||||
|
||||
def find_candidates_band(
|
||||
occupancy_grid: torch.Tensor,
|
||||
band_threshold: float,
|
||||
n_limits: int = -1
|
||||
) -> torch.Tensor:
|
||||
"""
|
||||
Returns the coordinates of all voxels in the occupancy_grid where |value| < band_threshold.
|
||||
|
||||
Args:
|
||||
occupancy_grid (torch.Tensor): A 3D tensor of SDF values.
|
||||
band_threshold (float): The threshold below which |SDF| must be to include the voxel.
|
||||
n_limits (int): Maximum number of points to return (-1 for no limit)
|
||||
|
||||
Returns:
|
||||
torch.Tensor: A 2D tensor of coordinates (N x 3) where each row is [x, y, z].
|
||||
"""
|
||||
core_grid = occupancy_grid[1:-1, 1:-1, 1:-1]
|
||||
# logits to sdf
|
||||
core_grid = torch.sigmoid(core_grid) * 2 - 1
|
||||
# Create a boolean mask for all cells in the band
|
||||
in_band = torch.abs(core_grid) < band_threshold
|
||||
|
||||
# Get coordinates of all voxels in the band
|
||||
core_mesh_coords = torch.nonzero(in_band, as_tuple=False) + 1
|
||||
|
||||
if n_limits != -1 and core_mesh_coords.shape[0] > n_limits:
|
||||
print(f"core mesh coords {core_mesh_coords.shape[0]} is too large, limited to {n_limits}")
|
||||
ind = np.random.choice(core_mesh_coords.shape[0], n_limits, True)
|
||||
core_mesh_coords = core_mesh_coords[ind]
|
||||
|
||||
return core_mesh_coords
|
||||
|
||||
def expand_edge_region_fast(edge_coords, grid_size, dtype):
|
||||
expanded_tensor = torch.zeros(grid_size, grid_size, grid_size, device='cuda', dtype=dtype, requires_grad=False)
|
||||
expanded_tensor[edge_coords[:, 0], edge_coords[:, 1], edge_coords[:, 2]] = 1
|
||||
if grid_size < 512:
|
||||
kernel_size = 5
|
||||
pooled_tensor = torch.nn.functional.max_pool3d(expanded_tensor.unsqueeze(0).unsqueeze(0), kernel_size=kernel_size, stride=1, padding=2).squeeze()
|
||||
else:
|
||||
kernel_size = 3
|
||||
pooled_tensor = torch.nn.functional.max_pool3d(expanded_tensor.unsqueeze(0).unsqueeze(0), kernel_size=kernel_size, stride=1, padding=1).squeeze()
|
||||
expanded_coords_low_res = torch.nonzero(pooled_tensor, as_tuple=False).to(torch.int16)
|
||||
|
||||
expanded_coords_high_res = torch.stack([
|
||||
torch.cat((expanded_coords_low_res[:, 0] * 2, expanded_coords_low_res[:, 0] * 2, expanded_coords_low_res[:, 0] * 2, expanded_coords_low_res[:, 0] * 2, expanded_coords_low_res[:, 0] * 2 + 1, expanded_coords_low_res[:, 0] * 2 + 1, expanded_coords_low_res[:, 0] * 2 + 1, expanded_coords_low_res[:, 0] * 2 + 1)),
|
||||
torch.cat((expanded_coords_low_res[:, 1] * 2, expanded_coords_low_res[:, 1] * 2, expanded_coords_low_res[:, 1] * 2+1, expanded_coords_low_res[:, 1] * 2 + 1, expanded_coords_low_res[:, 1] * 2, expanded_coords_low_res[:, 1] * 2, expanded_coords_low_res[:, 1] * 2 + 1, expanded_coords_low_res[:, 1] * 2 + 1)),
|
||||
torch.cat((expanded_coords_low_res[:, 2] * 2, expanded_coords_low_res[:, 2] * 2+1, expanded_coords_low_res[:, 2] * 2, expanded_coords_low_res[:, 2] * 2 + 1, expanded_coords_low_res[:, 2] * 2, expanded_coords_low_res[:, 2] * 2+1, expanded_coords_low_res[:, 2] * 2, expanded_coords_low_res[:, 2] * 2 + 1))
|
||||
], dim=1)
|
||||
|
||||
return expanded_coords_high_res
|
||||
|
||||
def zoom_block(block, scale_factor, order=3):
|
||||
block = block.astype(np.float32)
|
||||
return scipy.ndimage.zoom(block, scale_factor, order=order)
|
||||
|
||||
def parallel_zoom(occupancy_grid, scale_factor):
|
||||
result = torch.nn.functional.interpolate(occupancy_grid.unsqueeze(0).unsqueeze(0), scale_factor=scale_factor)
|
||||
return result.squeeze(0).squeeze(0)
|
||||
|
||||
|
||||
@torch.no_grad()
|
||||
def hierarchical_extract_geometry(
|
||||
geometric_func: Callable,
|
||||
device: torch.device,
|
||||
dtype: torch.dtype,
|
||||
bounds: Union[Tuple[float], List[float], float] = (-1.25, -1.25, -1.25, 1.25, 1.25, 1.25),
|
||||
dense_octree_depth: int = 8,
|
||||
hierarchical_octree_depth: int = 9,
|
||||
max_num_expanded_coords: int = 1e8,
|
||||
verbose: bool = False,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
geometric_func:
|
||||
device:
|
||||
bounds:
|
||||
dense_octree_depth:
|
||||
hierarchical_octree_depth:
|
||||
Returns:
|
||||
"""
|
||||
if isinstance(bounds, float):
|
||||
bounds = [-bounds, -bounds, -bounds, bounds, bounds, bounds]
|
||||
|
||||
bbox_min = torch.tensor(bounds[0:3]).to(device)
|
||||
bbox_max = torch.tensor(bounds[3:6]).to(device)
|
||||
bbox_size = bbox_max - bbox_min
|
||||
|
||||
xyz_samples, grid_size, length = generate_dense_grid_points_gpu(
|
||||
bbox_min=bbox_min,
|
||||
bbox_max=bbox_max,
|
||||
octree_depth=dense_octree_depth,
|
||||
indexing="ij",
|
||||
dtype=dtype
|
||||
)
|
||||
|
||||
if verbose:
|
||||
print(f'step 1 query num: {xyz_samples.shape[0]}')
|
||||
grid_logits = geometric_func(xyz_samples.unsqueeze(0)).to(dtype).view(grid_size[0], grid_size[1], grid_size[2])
|
||||
# print(f'step 1 grid_logits shape: {grid_logits.shape}')
|
||||
for i in range(hierarchical_octree_depth - dense_octree_depth):
|
||||
curr_octree_depth = dense_octree_depth + i + 1
|
||||
# upsample
|
||||
grid_size = 2**curr_octree_depth
|
||||
normalize_offset = grid_size / 2
|
||||
high_res_occupancy = parallel_zoom(grid_logits, 2).to(dtype)
|
||||
|
||||
band_threshold = 1.0
|
||||
edge_coords = find_candidates_band(grid_logits, band_threshold)
|
||||
expanded_coords = expand_edge_region_fast(edge_coords, grid_size=int(grid_size/2), dtype=dtype).to(dtype)
|
||||
if verbose:
|
||||
print(f'step {i+2} query num: {len(expanded_coords)}')
|
||||
if max_num_expanded_coords > 0 and len(expanded_coords) > max_num_expanded_coords:
|
||||
raise ValueError(f"expanded_coords is too large, {len(expanded_coords)} > {max_num_expanded_coords}")
|
||||
expanded_coords_norm = (expanded_coords - normalize_offset) * (abs(bounds[0]) / normalize_offset)
|
||||
|
||||
all_logits = None
|
||||
|
||||
all_logits = geometric_func(expanded_coords_norm.unsqueeze(0)).to(dtype)
|
||||
all_logits = torch.cat([expanded_coords_norm, all_logits[0]], dim=1)
|
||||
# print("all logits shape = ", all_logits.shape)
|
||||
|
||||
indices = all_logits[..., :3]
|
||||
indices = indices * (normalize_offset / abs(bounds[0])) + normalize_offset
|
||||
indices = indices.type(torch.IntTensor)
|
||||
values = all_logits[:, 3]
|
||||
# breakpoint()
|
||||
high_res_occupancy[indices[:, 0], indices[:, 1], indices[:, 2]] = values
|
||||
grid_logits = high_res_occupancy
|
||||
# torch.cuda.empty_cache()
|
||||
|
||||
if verbose:
|
||||
print("final grids shape = ", grid_logits.shape)
|
||||
vertices, faces, normals, _ = measure.marching_cubes(grid_logits.float().cpu().numpy(), 0, method="lewiner")
|
||||
vertices = vertices / (2**hierarchical_octree_depth) * bbox_size.cpu().numpy() + bbox_min.cpu().numpy()
|
||||
mesh_v_f = (vertices.astype(np.float32), np.ascontiguousarray(faces))
|
||||
|
||||
return mesh_v_f
|
||||
@@ -0,0 +1,159 @@
|
||||
from partcrafter_src.utils.typing_utils import *
|
||||
|
||||
import trimesh
|
||||
import numpy as np
|
||||
from sklearn.neighbors import NearestNeighbors
|
||||
|
||||
def sample_from_mesh(
|
||||
mesh: trimesh.Trimesh,
|
||||
num_samples: Optional[int] = 10000,
|
||||
):
|
||||
if num_samples is None:
|
||||
return mesh.vertices
|
||||
else:
|
||||
return mesh.sample(num_samples)
|
||||
|
||||
def sample_two_meshes(
|
||||
mesh1: trimesh.Trimesh,
|
||||
mesh2: trimesh.Trimesh,
|
||||
num_samples: Optional[int] = 10000,
|
||||
):
|
||||
points1 = sample_from_mesh(mesh1, num_samples)
|
||||
points2 = sample_from_mesh(mesh2, num_samples)
|
||||
return points1, points2
|
||||
|
||||
def compute_nearest_distance(
|
||||
points1: np.ndarray,
|
||||
points2: np.ndarray,
|
||||
metric: str = 'l2'
|
||||
) -> np.ndarray:
|
||||
# Compute nearest neighbor distance from points1 to points2
|
||||
nn = NearestNeighbors(n_neighbors=1, leaf_size=30, algorithm='kd_tree', metric=metric).fit(points2)
|
||||
min_dist = nn.kneighbors(points1)[0]
|
||||
return min_dist
|
||||
|
||||
def compute_mutual_nearest_distance(
|
||||
points1: np.ndarray,
|
||||
points2: np.ndarray,
|
||||
metric: str = 'l2'
|
||||
) -> np.ndarray:
|
||||
min_1_to_2 = compute_nearest_distance(points1, points2, metric=metric)
|
||||
min_2_to_1 = compute_nearest_distance(points2, points1, metric=metric)
|
||||
return min_1_to_2, min_2_to_1
|
||||
|
||||
def compute_mutual_nearest_distance_for_meshes(
|
||||
mesh1: trimesh.Trimesh,
|
||||
mesh2: trimesh.Trimesh,
|
||||
num_samples: Optional[int] = 10000,
|
||||
metric: str = 'l2'
|
||||
) -> Tuple[np.ndarray, np.ndarray]:
|
||||
points1 = sample_from_mesh(mesh1, num_samples)
|
||||
points2 = sample_from_mesh(mesh2, num_samples)
|
||||
min_1_to_2, min_2_to_1 = compute_mutual_nearest_distance(points1, points2, metric=metric)
|
||||
return min_1_to_2, min_2_to_1
|
||||
|
||||
def compute_chamfer_distance(
|
||||
mesh1: trimesh.Trimesh,
|
||||
mesh2: trimesh.Trimesh,
|
||||
num_samples: int = 10000,
|
||||
metric: str = 'l2'
|
||||
):
|
||||
min_1_to_2, min_2_to_1 = compute_mutual_nearest_distance_for_meshes(mesh1, mesh2, num_samples, metric=metric)
|
||||
chamfer_dist = np.mean(min_2_to_1) + np.mean(min_1_to_2)
|
||||
return chamfer_dist
|
||||
|
||||
def compute_f_score(
|
||||
mesh1: trimesh.Trimesh,
|
||||
mesh2: trimesh.Trimesh,
|
||||
num_samples: int = 10000,
|
||||
threshold: float = 0.1,
|
||||
metric: str = 'l2'
|
||||
):
|
||||
min_1_to_2, min_2_to_1 = compute_mutual_nearest_distance_for_meshes(mesh1, mesh2, num_samples, metric=metric)
|
||||
precision_1 = np.mean((min_1_to_2 < threshold).astype(np.float32))
|
||||
precision_2 = np.mean((min_2_to_1 < threshold).astype(np.float32))
|
||||
fscore = 2 * precision_1 * precision_2 / (precision_1 + precision_2)
|
||||
return fscore
|
||||
|
||||
def compute_cd_and_f_score(
|
||||
mesh1: trimesh.Trimesh,
|
||||
mesh2: trimesh.Trimesh,
|
||||
num_samples: Optional[int] = 10000,
|
||||
threshold: float = 0.1,
|
||||
metric: str = 'l2'
|
||||
):
|
||||
min_1_to_2, min_2_to_1 = compute_mutual_nearest_distance_for_meshes(mesh1, mesh2, num_samples, metric=metric)
|
||||
chamfer_dist = np.mean(min_2_to_1) + np.mean(min_1_to_2)
|
||||
precision_1 = np.mean((min_1_to_2 < threshold).astype(np.float32))
|
||||
precision_2 = np.mean((min_2_to_1 < threshold).astype(np.float32))
|
||||
fscore = 2 * precision_1 * precision_2 / (precision_1 + precision_2)
|
||||
return chamfer_dist, fscore
|
||||
|
||||
def compute_cd_and_f_score_in_training(
|
||||
gt_surface: np.ndarray,
|
||||
pred_mesh: trimesh.Trimesh,
|
||||
num_samples: int = 204800,
|
||||
threshold: float = 0.1,
|
||||
metric: str = 'l2'
|
||||
):
|
||||
gt_points = gt_surface[:, :3]
|
||||
num_samples = max(num_samples, gt_points.shape[0])
|
||||
gt_points = gt_points[np.random.choice(gt_points.shape[0], num_samples, replace=False)]
|
||||
pred_points = sample_from_mesh(pred_mesh, num_samples)
|
||||
min_1_to_2, min_2_to_1 = compute_mutual_nearest_distance(gt_points, pred_points, metric=metric)
|
||||
chamfer_dist = np.mean(min_2_to_1) + np.mean(min_1_to_2)
|
||||
precision_1 = np.mean((min_1_to_2 < threshold).astype(np.float32))
|
||||
precision_2 = np.mean((min_2_to_1 < threshold).astype(np.float32))
|
||||
fscore = 2 * precision_1 * precision_2 / (precision_1 + precision_2)
|
||||
return chamfer_dist, fscore
|
||||
|
||||
def get_voxel_set(
|
||||
mesh: trimesh.Trimesh,
|
||||
num_grids: int = 64,
|
||||
scale: float = 2.0,
|
||||
):
|
||||
if not isinstance(mesh, trimesh.Trimesh):
|
||||
raise ValueError("mesh must be a trimesh.Trimesh object")
|
||||
pitch = scale / num_grids
|
||||
voxel_girds: trimesh.voxel.base.VoxelGrid = mesh.voxelized(pitch=pitch).fill()
|
||||
voxels = set(map(tuple, np.round(voxel_girds.points / pitch).astype(int)))
|
||||
return voxels
|
||||
|
||||
def compute_IoU(
|
||||
mesh1: trimesh.Trimesh,
|
||||
mesh2: trimesh.Trimesh,
|
||||
num_grids: int = 64,
|
||||
scale: float = 2.0,
|
||||
):
|
||||
if not isinstance(mesh1, trimesh.Trimesh) or not isinstance(mesh2, trimesh.Trimesh):
|
||||
raise ValueError("mesh1 and mesh2 must be trimesh.Trimesh objects")
|
||||
voxels1 = get_voxel_set(mesh1, num_grids, scale)
|
||||
voxels2 = get_voxel_set(mesh2, num_grids, scale)
|
||||
intersection = voxels1 & voxels2
|
||||
union = voxels1 | voxels2
|
||||
iou = len(intersection) / len(union) if len(union) > 0 else 0.0
|
||||
return iou
|
||||
|
||||
def compute_IoU_for_scene(
|
||||
scene: Union[trimesh.Scene, List[trimesh.Trimesh]],
|
||||
num_grids: int = 64,
|
||||
scale: float = 2.0,
|
||||
return_type: Literal["iou", "iou_list"] = "iou",
|
||||
):
|
||||
if isinstance(scene, trimesh.Scene):
|
||||
scene = scene.dump()
|
||||
if isinstance(scene, list) and len(scene) > 1 and isinstance(scene[0], trimesh.Trimesh):
|
||||
meshes = scene
|
||||
else:
|
||||
raise ValueError("scene must be a trimesh.Scene object or a list of trimesh.Trimesh objects")
|
||||
ious = []
|
||||
for i in range(len(meshes)):
|
||||
for j in range(i+1, len(meshes)):
|
||||
iou = compute_IoU(meshes[i], meshes[j], num_grids, scale)
|
||||
ious.append(iou)
|
||||
if return_type == "iou":
|
||||
return np.mean(ious)
|
||||
elif return_type == "iou_list":
|
||||
return ious
|
||||
else:
|
||||
raise ValueError("return_type must be 'iou' or 'iou_list'")
|
||||
@@ -0,0 +1,411 @@
|
||||
from partcrafter_src.utils.typing_utils import *
|
||||
|
||||
import os
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
import trimesh
|
||||
from trimesh.transformations import rotation_matrix
|
||||
import pyrender
|
||||
from diffusers.utils import export_to_video
|
||||
from diffusers.utils.loading_utils import load_video
|
||||
import torch
|
||||
from torchvision.utils import make_grid
|
||||
|
||||
os.environ['PYOPENGL_PLATFORM'] = 'egl'
|
||||
|
||||
def render(
|
||||
scene: pyrender.Scene,
|
||||
renderer: pyrender.Renderer,
|
||||
camera: pyrender.Camera,
|
||||
pose: np.ndarray,
|
||||
light: Optional[pyrender.Light] = None,
|
||||
normalize_depth: bool = False,
|
||||
flags: int = pyrender.constants.RenderFlags.NONE,
|
||||
return_type: Literal['pil', 'ndarray'] = 'pil'
|
||||
) -> Union[Tuple[np.ndarray, np.ndarray], Tuple[Image.Image, Image.Image]]:
|
||||
camera_node = scene.add(camera, pose=pose)
|
||||
if light is not None:
|
||||
light_node = scene.add(light, pose=pose)
|
||||
image, depth = renderer.render(
|
||||
scene,
|
||||
flags=flags
|
||||
)
|
||||
scene.remove_node(camera_node)
|
||||
if light is not None:
|
||||
scene.remove_node(light_node)
|
||||
if normalize_depth or return_type == 'pil':
|
||||
depth = (depth - depth.min()) / (depth.max() - depth.min()) * 255.0
|
||||
if return_type == 'pil':
|
||||
image = Image.fromarray(image)
|
||||
depth = Image.fromarray(depth.astype(np.uint8))
|
||||
return image, depth
|
||||
|
||||
def rotation_matrix_from_vectors(vec1, vec2):
|
||||
a, b = vec1 / np.linalg.norm(vec1), vec2 / np.linalg.norm(vec2)
|
||||
v = np.cross(a, b)
|
||||
c = np.dot(a, b)
|
||||
s = np.linalg.norm(v)
|
||||
if s == 0:
|
||||
return np.eye(3) if c > 0 else -np.eye(3)
|
||||
kmat = np.array([
|
||||
[0, -v[2], v[1]],
|
||||
[v[2], 0, -v[0]],
|
||||
[-v[1], v[0], 0]
|
||||
])
|
||||
return np.eye(3) + kmat + kmat @ kmat * ((1 - c) / (s ** 2))
|
||||
|
||||
def create_circular_camera_positions(
|
||||
num_views: int,
|
||||
radius: float,
|
||||
axis: np.ndarray = np.array([0.0, 1.0, 0.0])
|
||||
) -> List[np.ndarray]:
|
||||
# Create a list of positions for a circular camera trajectory
|
||||
# around the given axis with the given radius.
|
||||
positions = []
|
||||
axis = axis / np.linalg.norm(axis)
|
||||
for i in range(num_views):
|
||||
theta = 2 * np.pi * i / num_views
|
||||
position = np.array([
|
||||
np.sin(theta) * radius,
|
||||
0.0,
|
||||
np.cos(theta) * radius
|
||||
])
|
||||
if not np.allclose(axis, np.array([0.0, 1.0, 0.0])):
|
||||
R = rotation_matrix_from_vectors(np.array([0.0, 1.0, 0.0]), axis)
|
||||
position = R @ position
|
||||
positions.append(position)
|
||||
return positions
|
||||
|
||||
def create_circular_camera_poses(
|
||||
num_views: int,
|
||||
radius: float,
|
||||
axis: np.ndarray = np.array([0.0, 1.0, 0.0])
|
||||
) -> List[np.ndarray]:
|
||||
# Create a list of poses for a circular camera trajectory
|
||||
# around the given axis with the given radius.
|
||||
# The camera always looks at the origin.
|
||||
# The up vector is always [0, 1, 0].
|
||||
canonical_pose = np.array([
|
||||
[1.0, 0.0, 0.0, 0.0],
|
||||
[0.0, 1.0, 0.0, 0.0],
|
||||
[0.0, 0.0, 1.0, radius],
|
||||
[0.0, 0.0, 0.0, 1.0]
|
||||
])
|
||||
poses = []
|
||||
for i in range(num_views):
|
||||
theta = 2 * np.pi * i / num_views
|
||||
R = rotation_matrix(
|
||||
angle=theta,
|
||||
direction=axis,
|
||||
point=[0, 0, 0]
|
||||
)
|
||||
pose = R @ canonical_pose
|
||||
poses.append(pose)
|
||||
return poses
|
||||
|
||||
def render_views_around_mesh(
|
||||
mesh: Union[trimesh.Trimesh, trimesh.Scene],
|
||||
num_views: int = 36,
|
||||
radius: float = 3.5,
|
||||
axis: np.ndarray = np.array([0.0, 1.0, 0.0]),
|
||||
image_size: tuple = (512, 512),
|
||||
fov: float = 40.0,
|
||||
light_intensity: Optional[float] = 5.0,
|
||||
znear: float = 0.1,
|
||||
zfar: float = 10.0,
|
||||
normalize_depth: bool = False,
|
||||
flags: int = pyrender.constants.RenderFlags.NONE,
|
||||
return_depth: bool = False,
|
||||
return_type: Literal['pil', 'ndarray'] = 'pil'
|
||||
) -> Union[
|
||||
List[Image.Image],
|
||||
List[np.ndarray],
|
||||
Tuple[List[Image.Image], List[Image.Image]],
|
||||
Tuple[List[np.ndarray], List[np.ndarray]]
|
||||
]:
|
||||
|
||||
if not isinstance(mesh, (trimesh.Trimesh, trimesh.Scene)):
|
||||
raise ValueError("mesh must be a trimesh.Trimesh or trimesh.Scene object")
|
||||
if isinstance(mesh, trimesh.Trimesh):
|
||||
mesh = trimesh.Scene(mesh)
|
||||
|
||||
scene = pyrender.Scene.from_trimesh_scene(mesh)
|
||||
light = pyrender.DirectionalLight(
|
||||
color=np.ones(3),
|
||||
intensity=light_intensity
|
||||
) if light_intensity is not None else None
|
||||
camera = pyrender.PerspectiveCamera(
|
||||
yfov=np.deg2rad(fov),
|
||||
aspectRatio=image_size[0]/image_size[1],
|
||||
znear=znear,
|
||||
zfar=zfar
|
||||
)
|
||||
renderer = pyrender.OffscreenRenderer(*image_size)
|
||||
|
||||
camera_poses = create_circular_camera_poses(
|
||||
num_views,
|
||||
radius,
|
||||
axis = axis
|
||||
)
|
||||
|
||||
images, depths = [], []
|
||||
for pose in camera_poses:
|
||||
image, depth = render(
|
||||
scene, renderer, camera, pose, light,
|
||||
normalize_depth=normalize_depth,
|
||||
flags=flags,
|
||||
return_type=return_type
|
||||
)
|
||||
images.append(image)
|
||||
depths.append(depth)
|
||||
|
||||
renderer.delete()
|
||||
|
||||
if return_depth:
|
||||
return images, depths
|
||||
return images
|
||||
|
||||
def render_normal_views_around_mesh(
|
||||
mesh: Union[trimesh.Trimesh, trimesh.Scene],
|
||||
num_views: int = 36,
|
||||
radius: float = 3.5,
|
||||
axis: np.ndarray = np.array([0.0, 1.0, 0.0]),
|
||||
image_size: tuple = (512, 512),
|
||||
fov: float = 40.0,
|
||||
light_intensity: Optional[float] = 5.0,
|
||||
znear: float = 0.1,
|
||||
zfar: float = 10.0,
|
||||
normalize_depth: bool = False,
|
||||
flags: int = pyrender.constants.RenderFlags.NONE,
|
||||
return_depth: bool = False,
|
||||
return_type: Literal['pil', 'ndarray'] = 'pil'
|
||||
) -> Union[
|
||||
List[Image.Image],
|
||||
List[np.ndarray],
|
||||
Tuple[List[Image.Image], List[Image.Image]],
|
||||
Tuple[List[np.ndarray], List[np.ndarray]]
|
||||
]:
|
||||
|
||||
if not isinstance(mesh, (trimesh.Trimesh, trimesh.Scene)):
|
||||
raise ValueError("mesh must be a trimesh.Trimesh or trimesh.Scene object")
|
||||
if isinstance(mesh, trimesh.Scene):
|
||||
mesh = mesh.to_geometry()
|
||||
normals = mesh.vertex_normals
|
||||
colors = ((normals + 1.0) / 2.0 * 255).astype(np.uint8)
|
||||
mesh.visual = trimesh.visual.ColorVisuals(
|
||||
mesh=mesh,
|
||||
vertex_colors=colors
|
||||
)
|
||||
mesh = trimesh.Scene(mesh)
|
||||
return render_views_around_mesh(
|
||||
mesh, num_views, radius, axis,
|
||||
image_size, fov, light_intensity, znear, zfar,
|
||||
normalize_depth, flags,
|
||||
return_depth, return_type
|
||||
)
|
||||
|
||||
def create_camera_pose_on_sphere(
|
||||
azimuth: float = 0.0, # in degrees
|
||||
elevation: float = 0.0, # in degrees
|
||||
radius: float = 3.5,
|
||||
) -> np.ndarray:
|
||||
# Create a camera pose for a given azimuth and elevation
|
||||
# with the given radius.
|
||||
# The camera always looks at the origin.
|
||||
# The up vector is always [0, 1, 0].
|
||||
canonical_pose = np.array([
|
||||
[1.0, 0.0, 0.0, 0.0],
|
||||
[0.0, 1.0, 0.0, 0.0],
|
||||
[0.0, 0.0, 1.0, radius],
|
||||
[0.0, 0.0, 0.0, 1.0]
|
||||
])
|
||||
azimuth = np.deg2rad(azimuth)
|
||||
elevation = np.deg2rad(elevation)
|
||||
position = np.array([
|
||||
np.cos(elevation) * np.sin(azimuth),
|
||||
np.sin(elevation),
|
||||
np.cos(elevation) * np.cos(azimuth),
|
||||
])
|
||||
R = np.eye(4)
|
||||
R[:3, :3] = rotation_matrix_from_vectors(
|
||||
np.array([0.0, 0.0, 1.0]),
|
||||
position
|
||||
)
|
||||
pose = R @ canonical_pose
|
||||
return pose
|
||||
|
||||
def render_single_view(
|
||||
mesh: Union[trimesh.Trimesh, trimesh.Scene],
|
||||
azimuth: float = 0.0, # in degrees
|
||||
elevation: float = 0.0, # in degrees
|
||||
radius: float = 3.5,
|
||||
image_size: tuple = (512, 512),
|
||||
fov: float = 40.0,
|
||||
light_intensity: Optional[float] = 5.0,
|
||||
num_env_lights: int = 0,
|
||||
znear: float = 0.1,
|
||||
zfar: float = 10.0,
|
||||
normalize_depth: bool = False,
|
||||
flags: int = pyrender.constants.RenderFlags.NONE,
|
||||
return_depth: bool = False,
|
||||
return_type: Literal['pil', 'ndarray'] = 'pil'
|
||||
) -> Union[
|
||||
Image.Image,
|
||||
np.ndarray,
|
||||
Tuple[Image.Image, Image.Image],
|
||||
Tuple[np.ndarray, np.ndarray]
|
||||
]:
|
||||
|
||||
if not isinstance(mesh, (trimesh.Trimesh, trimesh.Scene)):
|
||||
raise ValueError("mesh must be a trimesh.Trimesh or trimesh.Scene object")
|
||||
if isinstance(mesh, trimesh.Trimesh):
|
||||
mesh = trimesh.Scene(mesh)
|
||||
|
||||
scene = pyrender.Scene.from_trimesh_scene(mesh)
|
||||
light = pyrender.DirectionalLight(
|
||||
color=np.ones(3),
|
||||
intensity=light_intensity
|
||||
) if light_intensity is not None else None
|
||||
camera = pyrender.PerspectiveCamera(
|
||||
yfov=np.deg2rad(fov),
|
||||
aspectRatio=image_size[0]/image_size[1],
|
||||
znear=znear,
|
||||
zfar=zfar
|
||||
)
|
||||
renderer = pyrender.OffscreenRenderer(*image_size)
|
||||
|
||||
camera_pose = create_camera_pose_on_sphere(
|
||||
azimuth,
|
||||
elevation,
|
||||
radius
|
||||
)
|
||||
|
||||
if num_env_lights > 0:
|
||||
env_light_poses = create_circular_camera_poses(
|
||||
num_env_lights,
|
||||
radius,
|
||||
axis = np.array([0.0, 1.0, 0.0])
|
||||
)
|
||||
for pose in env_light_poses:
|
||||
scene.add(pyrender.DirectionalLight(
|
||||
color=np.ones(3),
|
||||
intensity=light_intensity
|
||||
), pose=pose)
|
||||
# set light to None
|
||||
light = None
|
||||
|
||||
image, depth = render(
|
||||
scene, renderer, camera, camera_pose, light,
|
||||
normalize_depth=normalize_depth,
|
||||
flags=flags,
|
||||
return_type=return_type
|
||||
)
|
||||
renderer.delete()
|
||||
|
||||
if return_depth:
|
||||
return image, depth
|
||||
return image
|
||||
|
||||
def render_normal_single_view(
|
||||
mesh: Union[trimesh.Trimesh, trimesh.Scene],
|
||||
azimuth: float = 0.0, # in degrees
|
||||
elevation: float = 0.0, # in degrees
|
||||
radius: float = 3.5,
|
||||
image_size: tuple = (512, 512),
|
||||
fov: float = 40.0,
|
||||
light_intensity: Optional[float] = 5.0,
|
||||
znear: float = 0.1,
|
||||
zfar: float = 10.0,
|
||||
normalize_depth: bool = False,
|
||||
flags: int = pyrender.constants.RenderFlags.NONE,
|
||||
return_depth: bool = False,
|
||||
return_type: Literal['pil', 'ndarray'] = 'pil'
|
||||
) -> Union[
|
||||
Image.Image,
|
||||
np.ndarray,
|
||||
Tuple[Image.Image, Image.Image],
|
||||
Tuple[np.ndarray, np.ndarray]
|
||||
]:
|
||||
|
||||
if not isinstance(mesh, (trimesh.Trimesh, trimesh.Scene)):
|
||||
raise ValueError("mesh must be a trimesh.Trimesh or trimesh.Scene object")
|
||||
if isinstance(mesh, trimesh.Scene):
|
||||
mesh = mesh.to_geometry()
|
||||
normals = mesh.vertex_normals
|
||||
colors = ((normals + 1.0) / 2.0 * 255).astype(np.uint8)
|
||||
mesh.visual = trimesh.visual.ColorVisuals(
|
||||
mesh=mesh,
|
||||
vertex_colors=colors
|
||||
)
|
||||
mesh = trimesh.Scene(mesh)
|
||||
return render_single_view(
|
||||
mesh, azimuth, elevation, radius,
|
||||
image_size, fov, light_intensity, znear, zfar,
|
||||
normalize_depth, flags,
|
||||
return_depth, return_type
|
||||
)
|
||||
|
||||
def export_renderings(
|
||||
images: List[Image.Image],
|
||||
export_path: str,
|
||||
fps: int = 36,
|
||||
loop: int = 0
|
||||
):
|
||||
export_type = export_path.split('.')[-1]
|
||||
if export_type == 'mp4':
|
||||
export_to_video(
|
||||
images,
|
||||
export_path,
|
||||
fps=fps,
|
||||
)
|
||||
elif export_type == 'gif':
|
||||
duration = 1000 / fps
|
||||
images[0].save(
|
||||
export_path,
|
||||
save_all=True,
|
||||
append_images=images[1:],
|
||||
duration=duration,
|
||||
loop=loop
|
||||
)
|
||||
else:
|
||||
raise ValueError(f'Unknown export type: {export_type}')
|
||||
|
||||
def make_grid_for_images_or_videos(
|
||||
images_or_videos: Union[List[Image.Image], List[List[Image.Image]]],
|
||||
nrow: int = 4,
|
||||
padding: int = 0,
|
||||
pad_value: int = 0,
|
||||
image_size: tuple = (512, 512),
|
||||
return_type: Literal['pil', 'ndarray'] = 'pil'
|
||||
) -> Union[Image.Image, List[Image.Image], np.ndarray]:
|
||||
if isinstance(images_or_videos[0], Image.Image):
|
||||
images = [np.array(image.resize(image_size).convert('RGB')) for image in images_or_videos]
|
||||
images = np.stack(images, axis=0).transpose(0, 3, 1, 2) # [N, C, H, W]
|
||||
images = torch.from_numpy(images)
|
||||
image_grid = make_grid(
|
||||
images,
|
||||
nrow=nrow,
|
||||
padding=padding,
|
||||
pad_value=pad_value,
|
||||
normalize=False
|
||||
) # [C, H', W']
|
||||
image_grid = image_grid.cpu().numpy()
|
||||
if return_type == 'pil':
|
||||
image_grid = Image.fromarray(image_grid.transpose(1, 2, 0))
|
||||
return image_grid
|
||||
elif isinstance(images_or_videos[0], list) and isinstance(images_or_videos[0][0], Image.Image):
|
||||
image_grids = []
|
||||
for i in range(len(images_or_videos[0])):
|
||||
images = [video[i] for video in images_or_videos]
|
||||
image_grid = make_grid_for_images_or_videos(
|
||||
images,
|
||||
nrow=nrow,
|
||||
padding=padding,
|
||||
return_type=return_type
|
||||
)
|
||||
image_grids.append(image_grid)
|
||||
if return_type == 'ndarray':
|
||||
image_grids = np.stack(image_grids, axis=0)
|
||||
return image_grids
|
||||
else:
|
||||
raise ValueError(f'Unknown input type: {type(images_or_videos[0])}')
|
||||
@@ -0,0 +1,643 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
# Copyright (c) 2012-2015, P. M. Neila
|
||||
# All rights reserved.
|
||||
|
||||
# Redistribution and use in source and binary forms, with or without
|
||||
# modification, are permitted provided that the following conditions are met:
|
||||
|
||||
# * Redistributions of source code must retain the above copyright notice, this
|
||||
# list of conditions and the following disclaimer.
|
||||
|
||||
# * Redistributions in binary form must reproduce the above copyright notice,
|
||||
# this list of conditions and the following disclaimer in the documentation
|
||||
# and/or other materials provided with the distribution.
|
||||
|
||||
# * Neither the name of the copyright holder nor the names of its
|
||||
# contributors may be used to endorse or promote products derived from
|
||||
# this software without specific prior written permission.
|
||||
|
||||
# THIS SOFTWARE IS PROVIDED BY THE COPYRIGHT HOLDERS AND CONTRIBUTORS "AS IS"
|
||||
# AND ANY EXPRESS OR IMPLIED WARRANTIES, INCLUDING, BUT NOT LIMITED TO, THE
|
||||
# IMPLIED WARRANTIES OF MERCHANTABILITY AND FITNESS FOR A PARTICULAR PURPOSE ARE
|
||||
# DISCLAIMED. IN NO EVENT SHALL THE COPYRIGHT HOLDER OR CONTRIBUTORS BE LIABLE
|
||||
# FOR ANY DIRECT, INDIRECT, INCIDENTAL, SPECIAL, EXEMPLARY, OR CONSEQUENTIAL
|
||||
# DAMAGES (INCLUDING, BUT NOT LIMITED TO, PROCUREMENT OF SUBSTITUTE GOODS OR
|
||||
# SERVICES; LOSS OF USE, DATA, OR PROFITS; OR BUSINESS INTERRUPTION) HOWEVER
|
||||
# CAUSED AND ON ANY THEORY OF LIABILITY, WHETHER IN CONTRACT, STRICT LIABILITY,
|
||||
# OR TORT (INCLUDING NEGLIGENCE OR OTHERWISE) ARISING IN ANY WAY OUT OF THE USE
|
||||
# OF THIS SOFTWARE, EVEN IF ADVISED OF THE POSSIBILITY OF SUCH DAMAGE.
|
||||
|
||||
"""
|
||||
Utilities for smoothing the occ/sdf grids.
|
||||
"""
|
||||
|
||||
import logging
|
||||
from typing import Tuple
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from scipy import ndimage as ndi
|
||||
from scipy import sparse
|
||||
|
||||
__all__ = [
|
||||
"smooth",
|
||||
"smooth_constrained",
|
||||
"smooth_gaussian",
|
||||
"signed_distance_function",
|
||||
"smooth_gpu",
|
||||
"smooth_constrained_gpu",
|
||||
"smooth_gaussian_gpu",
|
||||
"signed_distance_function_gpu",
|
||||
]
|
||||
|
||||
|
||||
def _build_variable_indices(band: np.ndarray) -> np.ndarray:
|
||||
num_variables = np.count_nonzero(band)
|
||||
variable_indices = np.full(band.shape, -1, dtype=np.int_)
|
||||
variable_indices[band] = np.arange(num_variables)
|
||||
return variable_indices
|
||||
|
||||
|
||||
def _buildq3d(variable_indices: np.ndarray):
|
||||
"""
|
||||
Builds the filterq matrix for the given variables.
|
||||
"""
|
||||
|
||||
num_variables = variable_indices.max() + 1
|
||||
filterq = sparse.lil_matrix((3 * num_variables, num_variables))
|
||||
|
||||
# Pad variable_indices to simplify out-of-bounds accesses
|
||||
variable_indices = np.pad(
|
||||
variable_indices, [(0, 1), (0, 1), (0, 1)], mode="constant", constant_values=-1
|
||||
)
|
||||
|
||||
coords = np.nonzero(variable_indices >= 0)
|
||||
for count, (i, j, k) in enumerate(zip(*coords)):
|
||||
|
||||
assert variable_indices[i, j, k] == count
|
||||
|
||||
filterq[3 * count, count] = -2
|
||||
neighbor = variable_indices[i - 1, j, k]
|
||||
if neighbor >= 0:
|
||||
filterq[3 * count, neighbor] = 1
|
||||
else:
|
||||
filterq[3 * count, count] += 1
|
||||
|
||||
neighbor = variable_indices[i + 1, j, k]
|
||||
if neighbor >= 0:
|
||||
filterq[3 * count, neighbor] = 1
|
||||
else:
|
||||
filterq[3 * count, count] += 1
|
||||
|
||||
filterq[3 * count + 1, count] = -2
|
||||
neighbor = variable_indices[i, j - 1, k]
|
||||
if neighbor >= 0:
|
||||
filterq[3 * count + 1, neighbor] = 1
|
||||
else:
|
||||
filterq[3 * count + 1, count] += 1
|
||||
|
||||
neighbor = variable_indices[i, j + 1, k]
|
||||
if neighbor >= 0:
|
||||
filterq[3 * count + 1, neighbor] = 1
|
||||
else:
|
||||
filterq[3 * count + 1, count] += 1
|
||||
|
||||
filterq[3 * count + 2, count] = -2
|
||||
neighbor = variable_indices[i, j, k - 1]
|
||||
if neighbor >= 0:
|
||||
filterq[3 * count + 2, neighbor] = 1
|
||||
else:
|
||||
filterq[3 * count + 2, count] += 1
|
||||
|
||||
neighbor = variable_indices[i, j, k + 1]
|
||||
if neighbor >= 0:
|
||||
filterq[3 * count + 2, neighbor] = 1
|
||||
else:
|
||||
filterq[3 * count + 2, count] += 1
|
||||
|
||||
filterq = filterq.tocsr()
|
||||
return filterq.T.dot(filterq)
|
||||
|
||||
|
||||
def _buildq3d_gpu(variable_indices: torch.Tensor, chunk_size=10000):
|
||||
"""
|
||||
Builds the filterq matrix for the given variables on GPU, using chunking to reduce memory usage.
|
||||
"""
|
||||
device = variable_indices.device
|
||||
num_variables = variable_indices.max().item() + 1
|
||||
|
||||
# Pad variable_indices to simplify out-of-bounds accesses
|
||||
variable_indices = torch.nn.functional.pad(
|
||||
variable_indices, (0, 1, 0, 1, 0, 1), mode="constant", value=-1
|
||||
)
|
||||
|
||||
coords = torch.nonzero(variable_indices >= 0)
|
||||
i, j, k = coords[:, 0], coords[:, 1], coords[:, 2]
|
||||
|
||||
# Function to process a chunk of data
|
||||
def process_chunk(start, end):
|
||||
row_indices = []
|
||||
col_indices = []
|
||||
values = []
|
||||
|
||||
for axis in range(3):
|
||||
row_indices.append(3 * torch.arange(start, end, device=device) + axis)
|
||||
col_indices.append(
|
||||
variable_indices[i[start:end], j[start:end], k[start:end]]
|
||||
)
|
||||
values.append(torch.full((end - start,), -2, device=device))
|
||||
|
||||
for offset in [-1, 1]:
|
||||
if axis == 0:
|
||||
neighbor = variable_indices[
|
||||
i[start:end] + offset, j[start:end], k[start:end]
|
||||
]
|
||||
elif axis == 1:
|
||||
neighbor = variable_indices[
|
||||
i[start:end], j[start:end] + offset, k[start:end]
|
||||
]
|
||||
else:
|
||||
neighbor = variable_indices[
|
||||
i[start:end], j[start:end], k[start:end] + offset
|
||||
]
|
||||
|
||||
mask = neighbor >= 0
|
||||
row_indices.append(
|
||||
3 * torch.arange(start, end, device=device)[mask] + axis
|
||||
)
|
||||
col_indices.append(neighbor[mask])
|
||||
values.append(torch.ones(mask.sum(), device=device))
|
||||
|
||||
# Add 1 to the diagonal for out-of-bounds neighbors
|
||||
row_indices.append(
|
||||
3 * torch.arange(start, end, device=device)[~mask] + axis
|
||||
)
|
||||
col_indices.append(
|
||||
variable_indices[i[start:end], j[start:end], k[start:end]][~mask]
|
||||
)
|
||||
values.append(torch.ones((~mask).sum(), device=device))
|
||||
|
||||
return torch.cat(row_indices), torch.cat(col_indices), torch.cat(values)
|
||||
|
||||
# Process data in chunks
|
||||
all_row_indices = []
|
||||
all_col_indices = []
|
||||
all_values = []
|
||||
|
||||
for start in range(0, coords.shape[0], chunk_size):
|
||||
end = min(start + chunk_size, coords.shape[0])
|
||||
row_indices, col_indices, values = process_chunk(start, end)
|
||||
all_row_indices.append(row_indices)
|
||||
all_col_indices.append(col_indices)
|
||||
all_values.append(values)
|
||||
|
||||
# Concatenate all chunks
|
||||
row_indices = torch.cat(all_row_indices)
|
||||
col_indices = torch.cat(all_col_indices)
|
||||
values = torch.cat(all_values)
|
||||
|
||||
# Create sparse tensor
|
||||
indices = torch.stack([row_indices, col_indices])
|
||||
filterq = torch.sparse_coo_tensor(
|
||||
indices, values, (3 * num_variables, num_variables)
|
||||
)
|
||||
|
||||
# Compute filterq.T @ filterq
|
||||
return torch.sparse.mm(filterq.t(), filterq)
|
||||
|
||||
|
||||
# Usage example:
|
||||
# variable_indices = torch.tensor(...).cuda() # Your input tensor on GPU
|
||||
# result = _buildq3d_gpu(variable_indices)
|
||||
|
||||
|
||||
def _buildq2d(variable_indices: np.ndarray):
|
||||
"""
|
||||
Builds the filterq matrix for the given variables.
|
||||
|
||||
Version for 2 dimensions.
|
||||
"""
|
||||
|
||||
num_variables = variable_indices.max() + 1
|
||||
filterq = sparse.lil_matrix((3 * num_variables, num_variables))
|
||||
|
||||
# Pad variable_indices to simplify out-of-bounds accesses
|
||||
variable_indices = np.pad(
|
||||
variable_indices, [(0, 1), (0, 1)], mode="constant", constant_values=-1
|
||||
)
|
||||
|
||||
coords = np.nonzero(variable_indices >= 0)
|
||||
for count, (i, j) in enumerate(zip(*coords)):
|
||||
assert variable_indices[i, j] == count
|
||||
|
||||
filterq[2 * count, count] = -2
|
||||
neighbor = variable_indices[i - 1, j]
|
||||
if neighbor >= 0:
|
||||
filterq[2 * count, neighbor] = 1
|
||||
else:
|
||||
filterq[2 * count, count] += 1
|
||||
|
||||
neighbor = variable_indices[i + 1, j]
|
||||
if neighbor >= 0:
|
||||
filterq[2 * count, neighbor] = 1
|
||||
else:
|
||||
filterq[2 * count, count] += 1
|
||||
|
||||
filterq[2 * count + 1, count] = -2
|
||||
neighbor = variable_indices[i, j - 1]
|
||||
if neighbor >= 0:
|
||||
filterq[2 * count + 1, neighbor] = 1
|
||||
else:
|
||||
filterq[2 * count + 1, count] += 1
|
||||
|
||||
neighbor = variable_indices[i, j + 1]
|
||||
if neighbor >= 0:
|
||||
filterq[2 * count + 1, neighbor] = 1
|
||||
else:
|
||||
filterq[2 * count + 1, count] += 1
|
||||
|
||||
filterq = filterq.tocsr()
|
||||
return filterq.T.dot(filterq)
|
||||
|
||||
|
||||
def _jacobi(
|
||||
filterq,
|
||||
x0: np.ndarray,
|
||||
lower_bound: np.ndarray,
|
||||
upper_bound: np.ndarray,
|
||||
max_iters: int = 10,
|
||||
rel_tol: float = 1e-6,
|
||||
weight: float = 0.5,
|
||||
):
|
||||
"""Jacobi method with constraints."""
|
||||
|
||||
jacobi_r = sparse.lil_matrix(filterq)
|
||||
shp = jacobi_r.shape
|
||||
jacobi_d = 1.0 / filterq.diagonal()
|
||||
jacobi_r.setdiag((0,) * shp[0])
|
||||
jacobi_r = jacobi_r.tocsr()
|
||||
|
||||
x = x0
|
||||
|
||||
# We check the stopping criterion each 10 iterations
|
||||
check_each = 10
|
||||
cum_rel_tol = 1 - (1 - rel_tol) ** check_each
|
||||
|
||||
energy_now = np.dot(x, filterq.dot(x)) / 2
|
||||
logging.info("Energy at iter %d: %.6g", 0, energy_now)
|
||||
for i in range(max_iters):
|
||||
|
||||
x_1 = -jacobi_d * jacobi_r.dot(x)
|
||||
x = weight * x_1 + (1 - weight) * x
|
||||
|
||||
# Constraints.
|
||||
x = np.maximum(x, lower_bound)
|
||||
x = np.minimum(x, upper_bound)
|
||||
|
||||
# Stopping criterion
|
||||
if (i + 1) % check_each == 0:
|
||||
# Update energy
|
||||
energy_before = energy_now
|
||||
energy_now = np.dot(x, filterq.dot(x)) / 2
|
||||
|
||||
logging.info("Energy at iter %d: %.6g", i + 1, energy_now)
|
||||
|
||||
# Check stopping criterion
|
||||
cum_rel_improvement = (energy_before - energy_now) / energy_before
|
||||
if cum_rel_improvement < cum_rel_tol:
|
||||
break
|
||||
|
||||
return x
|
||||
|
||||
|
||||
def signed_distance_function(
|
||||
levelset: np.ndarray, band_radius: int
|
||||
) -> Tuple[np.ndarray, np.ndarray, np.ndarray]:
|
||||
"""
|
||||
Return the distance to the 0.5 levelset of a function, the mask of the
|
||||
border (i.e., the nearest cells to the 0.5 level-set) and the mask of the
|
||||
band (i.e., the cells of the function whose distance to the 0.5 level-set
|
||||
is less of equal to `band_radius`).
|
||||
"""
|
||||
|
||||
binary_array = np.where(levelset > 0, True, False)
|
||||
|
||||
# Compute the band and the border.
|
||||
dist_func = ndi.distance_transform_edt
|
||||
distance = np.where(
|
||||
binary_array, dist_func(binary_array) - 0.5, -dist_func(~binary_array) + 0.5
|
||||
)
|
||||
border = np.abs(distance) < 1
|
||||
band = np.abs(distance) <= band_radius
|
||||
|
||||
return distance, border, band
|
||||
|
||||
|
||||
def signed_distance_function_iso0(
|
||||
levelset: np.ndarray, band_radius: int
|
||||
) -> Tuple[np.ndarray, np.ndarray, np.ndarray]:
|
||||
"""
|
||||
Return the distance to the 0 levelset of a function, the mask of the
|
||||
border (i.e., the nearest cells to the 0 level-set) and the mask of the
|
||||
band (i.e., the cells of the function whose distance to the 0 level-set
|
||||
is less of equal to `band_radius`).
|
||||
"""
|
||||
|
||||
binary_array = levelset > 0
|
||||
|
||||
# Compute the band and the border.
|
||||
dist_func = ndi.distance_transform_edt
|
||||
distance = np.where(
|
||||
binary_array, dist_func(binary_array), -dist_func(~binary_array)
|
||||
)
|
||||
border = np.zeros_like(levelset, dtype=bool)
|
||||
border[:-1, :, :] |= levelset[:-1, :, :] * levelset[1:, :, :] <= 0
|
||||
border[:, :-1, :] |= levelset[:, :-1, :] * levelset[:, 1:, :] <= 0
|
||||
border[:, :, :-1] |= levelset[:, :, :-1] * levelset[:, :, 1:] <= 0
|
||||
band = np.abs(distance) <= band_radius
|
||||
|
||||
return distance, border, band
|
||||
|
||||
|
||||
def signed_distance_function_gpu(levelset: torch.Tensor, band_radius: int):
|
||||
binary_array = (levelset > 0).float()
|
||||
|
||||
# Compute distance transform
|
||||
dist_pos = (
|
||||
F.max_pool3d(
|
||||
-binary_array.unsqueeze(0).unsqueeze(0), kernel_size=3, stride=1, padding=1
|
||||
)
|
||||
.squeeze(0)
|
||||
.squeeze(0)
|
||||
+ binary_array
|
||||
)
|
||||
dist_neg = F.max_pool3d(
|
||||
(binary_array - 1).unsqueeze(0).unsqueeze(0), kernel_size=3, stride=1, padding=1
|
||||
).squeeze(0).squeeze(0) + (1 - binary_array)
|
||||
|
||||
distance = torch.where(binary_array > 0, dist_pos - 0.5, -dist_neg + 0.5)
|
||||
|
||||
# breakpoint()
|
||||
|
||||
# Use levelset as distance directly
|
||||
# distance = levelset
|
||||
# print(distance.shape)
|
||||
# Compute border and band
|
||||
border = torch.abs(distance) < 1
|
||||
band = torch.abs(distance) <= band_radius
|
||||
|
||||
return distance, border, band
|
||||
|
||||
|
||||
def smooth_constrained(
|
||||
binary_array: np.ndarray,
|
||||
band_radius: int = 4,
|
||||
max_iters: int = 250,
|
||||
rel_tol: float = 1e-6,
|
||||
) -> np.ndarray:
|
||||
"""
|
||||
Implementation of the smoothing method from
|
||||
|
||||
"Surface Extraction from Binary Volumes with Higher-Order Smoothness"
|
||||
Victor Lempitsky, CVPR10
|
||||
"""
|
||||
|
||||
# # Compute the distance map, the border and the band.
|
||||
logging.info("Computing distance transform...")
|
||||
# distance, _, band = signed_distance_function(binary_array, band_radius)
|
||||
binary_array_gpu = torch.from_numpy(binary_array).cuda()
|
||||
distance, _, band = signed_distance_function_gpu(binary_array_gpu, band_radius)
|
||||
distance = distance.cpu().numpy()
|
||||
band = band.cpu().numpy()
|
||||
|
||||
variable_indices = _build_variable_indices(band)
|
||||
|
||||
# Compute filterq.
|
||||
logging.info("Building matrix filterq...")
|
||||
if binary_array.ndim == 3:
|
||||
filterq = _buildq3d(variable_indices)
|
||||
# variable_indices_gpu = torch.from_numpy(variable_indices).cuda()
|
||||
# filterq_gpu = _buildq3d_gpu(variable_indices_gpu)
|
||||
# filterq = filterq_gpu.cpu().numpy()
|
||||
elif binary_array.ndim == 2:
|
||||
filterq = _buildq2d(variable_indices)
|
||||
else:
|
||||
raise ValueError("binary_array.ndim not in [2, 3]")
|
||||
|
||||
# Initialize the variables.
|
||||
res = np.asarray(distance, dtype=np.double)
|
||||
x = res[band]
|
||||
upper_bound = np.where(x < 0, x, np.inf)
|
||||
lower_bound = np.where(x > 0, x, -np.inf)
|
||||
|
||||
upper_bound[np.abs(upper_bound) < 1] = 0
|
||||
lower_bound[np.abs(lower_bound) < 1] = 0
|
||||
|
||||
# Solve.
|
||||
logging.info("Minimizing energy...")
|
||||
x = _jacobi(
|
||||
filterq=filterq,
|
||||
x0=x,
|
||||
lower_bound=lower_bound,
|
||||
upper_bound=upper_bound,
|
||||
max_iters=max_iters,
|
||||
rel_tol=rel_tol,
|
||||
)
|
||||
|
||||
res[band] = x
|
||||
return res
|
||||
|
||||
|
||||
def total_variation_denoising(x, weight=0.1, num_iterations=5, eps=1e-8):
|
||||
diff_x = torch.diff(x, dim=0, prepend=x[:1])
|
||||
diff_y = torch.diff(x, dim=1, prepend=x[:, :1])
|
||||
diff_z = torch.diff(x, dim=2, prepend=x[:, :, :1])
|
||||
|
||||
norm = torch.sqrt(diff_x**2 + diff_y**2 + diff_z**2 + eps)
|
||||
|
||||
div_x = torch.diff(diff_x / norm, dim=0, append=diff_x[-1:] / norm[-1:])
|
||||
div_y = torch.diff(diff_y / norm, dim=1, append=diff_y[:, -1:] / norm[:, -1:])
|
||||
div_z = torch.diff(diff_z / norm, dim=2, append=diff_z[:, :, -1:] / norm[:, :, -1:])
|
||||
|
||||
return x - weight * (div_x + div_y + div_z)
|
||||
|
||||
|
||||
def smooth_constrained_gpu(
|
||||
binary_array: torch.Tensor,
|
||||
band_radius: int = 4,
|
||||
max_iters: int = 250,
|
||||
rel_tol: float = 1e-4,
|
||||
):
|
||||
distance, _, band = signed_distance_function_gpu(binary_array, band_radius)
|
||||
|
||||
# Initialize variables
|
||||
x = distance[band]
|
||||
upper_bound = torch.where(x < 0, x, torch.tensor(float("inf"), device=x.device))
|
||||
lower_bound = torch.where(x > 0, x, torch.tensor(float("-inf"), device=x.device))
|
||||
|
||||
upper_bound[torch.abs(upper_bound) < 1] = 0
|
||||
lower_bound[torch.abs(lower_bound) < 1] = 0
|
||||
|
||||
# Define the 3D Laplacian kernel
|
||||
laplacian_kernel = torch.tensor(
|
||||
[
|
||||
[
|
||||
[
|
||||
[[0, 1, 0], [1, -6, 1], [0, 1, 0]],
|
||||
[[1, 0, 1], [0, 0, 0], [1, 0, 1]],
|
||||
[[0, 1, 0], [1, 0, 1], [0, 1, 0]],
|
||||
]
|
||||
]
|
||||
],
|
||||
device=x.device,
|
||||
).float()
|
||||
|
||||
laplacian_kernel = laplacian_kernel / laplacian_kernel.abs().sum()
|
||||
|
||||
breakpoint()
|
||||
|
||||
# Simplified Jacobi iteration
|
||||
for i in range(max_iters):
|
||||
# Reshape x to 5D tensor (batch, channel, depth, height, width)
|
||||
x_5d = x.view(1, 1, *band.shape)
|
||||
x_3d = x.view(*band.shape)
|
||||
|
||||
# Apply 3D convolution
|
||||
laplacian = F.conv3d(x_5d, laplacian_kernel, padding=1)
|
||||
|
||||
# Reshape back to original dimensions
|
||||
laplacian = laplacian.view(x.shape)
|
||||
|
||||
# Use a small relaxation factor to improve stability
|
||||
relaxation_factor = 0.1
|
||||
tv_weight = 0.1
|
||||
# x_new = x + relaxation_factor * laplacian
|
||||
x_new = total_variation_denoising(x_3d, weight=tv_weight)
|
||||
# Print laplacian min and max
|
||||
# print(f"Laplacian min: {laplacian.min().item():.4f}, max: {laplacian.max().item():.4f}")
|
||||
|
||||
# Apply constraints
|
||||
# Reshape x_new to match the dimensions of lower_bound and upper_bound
|
||||
x_new = x_new.view(x.shape)
|
||||
x_new = torch.clamp(x_new, min=lower_bound, max=upper_bound)
|
||||
|
||||
# Check for convergence
|
||||
diff_norm = torch.norm(x_new - x)
|
||||
print(diff_norm)
|
||||
x_norm = torch.norm(x)
|
||||
|
||||
if x_norm > 1e-8: # Avoid division by very small numbers
|
||||
relative_change = diff_norm / x_norm
|
||||
if relative_change < rel_tol:
|
||||
break
|
||||
elif diff_norm < rel_tol: # If x_norm is very small, check absolute change
|
||||
break
|
||||
|
||||
x = x_new
|
||||
|
||||
# Check for NaN and break if found, also check for inf
|
||||
if torch.isnan(x).any() or torch.isinf(x).any():
|
||||
print(f"NaN or Inf detected at iteration {i}")
|
||||
breakpoint()
|
||||
break
|
||||
|
||||
result = distance.clone()
|
||||
result[band] = x
|
||||
return result
|
||||
|
||||
|
||||
def smooth_gaussian(binary_array: np.ndarray, sigma: float = 3) -> np.ndarray:
|
||||
vol = np.float_(binary_array) - 0.5
|
||||
return ndi.gaussian_filter(vol, sigma=sigma)
|
||||
|
||||
|
||||
def smooth_gaussian_gpu(binary_array: torch.Tensor, sigma: float = 3):
|
||||
# vol = binary_array.float()
|
||||
vol = binary_array
|
||||
kernel_size = int(2 * sigma + 1)
|
||||
kernel = torch.ones(
|
||||
1,
|
||||
1,
|
||||
kernel_size,
|
||||
kernel_size,
|
||||
kernel_size,
|
||||
device=binary_array.device,
|
||||
dtype=vol.dtype,
|
||||
) / (kernel_size**3)
|
||||
return F.conv3d(
|
||||
vol.unsqueeze(0).unsqueeze(0), kernel, padding=kernel_size // 2
|
||||
).squeeze()
|
||||
|
||||
|
||||
def smooth(binary_array: np.ndarray, method: str = "auto", **kwargs) -> np.ndarray:
|
||||
"""
|
||||
Smooths the 0.5 level-set of a binary array. Returns a floating-point
|
||||
array with a smoothed version of the original level-set in the 0 isovalue.
|
||||
|
||||
This function can apply two different methods:
|
||||
|
||||
- A constrained smoothing method which preserves details and fine
|
||||
structures, but it is slow and requires a large amount of memory. This
|
||||
method is recommended when the input array is small (smaller than
|
||||
(500, 500, 500)).
|
||||
- A Gaussian filter applied over the binary array. This method is fast, but
|
||||
not very precise, as it can destroy fine details. It is only recommended
|
||||
when the input array is large and the 0.5 level-set does not contain
|
||||
thin structures.
|
||||
|
||||
Parameters
|
||||
----------
|
||||
binary_array : ndarray
|
||||
Input binary array with the 0.5 level-set to smooth.
|
||||
method : str, one of ['auto', 'gaussian', 'constrained']
|
||||
Smoothing method. If 'auto' is given, the method will be automatically
|
||||
chosen based on the size of `binary_array`.
|
||||
|
||||
Parameters for 'gaussian'
|
||||
-------------------------
|
||||
sigma : float
|
||||
Size of the Gaussian filter (default 3).
|
||||
|
||||
Parameters for 'constrained'
|
||||
----------------------------
|
||||
max_iters : positive integer
|
||||
Number of iterations of the constrained optimization method
|
||||
(default 250).
|
||||
rel_tol: float
|
||||
Relative tolerance as a stopping criterion (default 1e-6).
|
||||
|
||||
Output
|
||||
------
|
||||
res : ndarray
|
||||
Floating-point array with a smoothed 0 level-set.
|
||||
"""
|
||||
|
||||
binary_array = np.asarray(binary_array)
|
||||
|
||||
if method == "auto":
|
||||
if binary_array.size > 512**3:
|
||||
method = "gaussian"
|
||||
else:
|
||||
method = "constrained"
|
||||
|
||||
if method == "gaussian":
|
||||
return smooth_gaussian(binary_array, **kwargs)
|
||||
|
||||
if method == "constrained":
|
||||
return smooth_constrained(binary_array, **kwargs)
|
||||
|
||||
raise ValueError("Unknown method '{}'".format(method))
|
||||
|
||||
|
||||
def smooth_gpu(binary_array: torch.Tensor, method: str = "auto", **kwargs):
|
||||
if method == "auto":
|
||||
method = "gaussian" if binary_array.numel() > 512**3 else "constrained"
|
||||
|
||||
if method == "gaussian":
|
||||
return smooth_gaussian_gpu(binary_array, **kwargs)
|
||||
elif method == "constrained":
|
||||
return smooth_constrained_gpu(binary_array, **kwargs)
|
||||
else:
|
||||
raise ValueError(f"Unknown method '{method}'")
|
||||
@@ -0,0 +1,184 @@
|
||||
from partcrafter_src.utils.typing_utils import *
|
||||
|
||||
import os
|
||||
from omegaconf import OmegaConf
|
||||
|
||||
from torch import optim
|
||||
from torch.optim import lr_scheduler
|
||||
from diffusers.training_utils import *
|
||||
from diffusers.optimization import get_scheduler
|
||||
|
||||
# https://github.com/huggingface/diffusers/pull/9812: fix `self.use_ema_warmup`
|
||||
class MyEMAModel(EMAModel):
|
||||
"""
|
||||
Exponential Moving Average of models weights
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
parameters: Iterable[torch.nn.Parameter],
|
||||
decay: float = 0.9999,
|
||||
min_decay: float = 0.0,
|
||||
update_after_step: int = 0,
|
||||
use_ema_warmup: bool = False,
|
||||
inv_gamma: Union[float, int] = 1.0,
|
||||
power: Union[float, int] = 2 / 3,
|
||||
foreach: bool = False,
|
||||
model_cls: Optional[Any] = None,
|
||||
model_config: Dict[str, Any] = None,
|
||||
**kwargs,
|
||||
):
|
||||
"""
|
||||
Args:
|
||||
parameters (Iterable[torch.nn.Parameter]): The parameters to track.
|
||||
decay (float): The decay factor for the exponential moving average.
|
||||
min_decay (float): The minimum decay factor for the exponential moving average.
|
||||
update_after_step (int): The number of steps to wait before starting to update the EMA weights.
|
||||
use_ema_warmup (bool): Whether to use EMA warmup.
|
||||
inv_gamma (float):
|
||||
Inverse multiplicative factor of EMA warmup. Default: 1. Only used if `use_ema_warmup` is True.
|
||||
power (float): Exponential factor of EMA warmup. Default: 2/3. Only used if `use_ema_warmup` is True.
|
||||
foreach (bool): Use torch._foreach functions for updating shadow parameters. Should be faster.
|
||||
device (Optional[Union[str, torch.device]]): The device to store the EMA weights on. If None, the EMA
|
||||
weights will be stored on CPU.
|
||||
|
||||
@crowsonkb's notes on EMA Warmup:
|
||||
If gamma=1 and power=1, implements a simple average. gamma=1, power=2/3 are good values for models you plan
|
||||
to train for a million or more steps (reaches decay factor 0.999 at 31.6K steps, 0.9999 at 1M steps),
|
||||
gamma=1, power=3/4 for models you plan to train for less (reaches decay factor 0.999 at 10K steps, 0.9999
|
||||
at 215.4k steps).
|
||||
"""
|
||||
|
||||
if isinstance(parameters, torch.nn.Module):
|
||||
deprecation_message = (
|
||||
"Passing a `torch.nn.Module` to `ExponentialMovingAverage` is deprecated. "
|
||||
"Please pass the parameters of the module instead."
|
||||
)
|
||||
deprecate(
|
||||
"passing a `torch.nn.Module` to `ExponentialMovingAverage`",
|
||||
"1.0.0",
|
||||
deprecation_message,
|
||||
standard_warn=False,
|
||||
)
|
||||
parameters = parameters.parameters()
|
||||
|
||||
# # set use_ema_warmup to True if a torch.nn.Module is passed for backwards compatibility
|
||||
# use_ema_warmup = True
|
||||
|
||||
if kwargs.get("max_value", None) is not None:
|
||||
deprecation_message = "The `max_value` argument is deprecated. Please use `decay` instead."
|
||||
deprecate("max_value", "1.0.0", deprecation_message, standard_warn=False)
|
||||
decay = kwargs["max_value"]
|
||||
|
||||
if kwargs.get("min_value", None) is not None:
|
||||
deprecation_message = "The `min_value` argument is deprecated. Please use `min_decay` instead."
|
||||
deprecate("min_value", "1.0.0", deprecation_message, standard_warn=False)
|
||||
min_decay = kwargs["min_value"]
|
||||
|
||||
parameters = list(parameters)
|
||||
self.shadow_params = [p.clone().detach() for p in parameters]
|
||||
|
||||
if kwargs.get("device", None) is not None:
|
||||
deprecation_message = "The `device` argument is deprecated. Please use `to` instead."
|
||||
deprecate("device", "1.0.0", deprecation_message, standard_warn=False)
|
||||
self.to(device=kwargs["device"])
|
||||
|
||||
self.temp_stored_params = None
|
||||
|
||||
self.decay = decay
|
||||
self.min_decay = min_decay
|
||||
self.update_after_step = update_after_step
|
||||
self.use_ema_warmup = use_ema_warmup
|
||||
self.inv_gamma = inv_gamma
|
||||
self.power = power
|
||||
self.optimization_step = 0
|
||||
self.cur_decay_value = None # set in `step()`
|
||||
self.foreach = foreach
|
||||
|
||||
self.model_cls = model_cls
|
||||
self.model_config = model_config
|
||||
|
||||
def get_decay(self, optimization_step: int) -> float:
|
||||
"""
|
||||
Compute the decay factor for the exponential moving average.
|
||||
"""
|
||||
step = max(0, optimization_step - self.update_after_step - 1)
|
||||
|
||||
if step <= 0:
|
||||
return 0.0
|
||||
|
||||
if self.use_ema_warmup:
|
||||
cur_decay_value = 1 - (1 + step / self.inv_gamma) ** -self.power
|
||||
else:
|
||||
# cur_decay_value = (1 + step) / (10 + step)
|
||||
cur_decay_value = self.decay
|
||||
|
||||
cur_decay_value = min(cur_decay_value, self.decay)
|
||||
# make sure decay is not smaller than min_decay
|
||||
cur_decay_value = max(cur_decay_value, self.min_decay)
|
||||
return cur_decay_value
|
||||
|
||||
def get_configs(yaml_path: str, cli_configs: List[str]=[], **kwargs) -> DictConfig:
|
||||
yaml_configs = OmegaConf.load(yaml_path)
|
||||
cli_configs = OmegaConf.from_cli(cli_configs)
|
||||
|
||||
configs = OmegaConf.merge(yaml_configs, cli_configs, kwargs)
|
||||
OmegaConf.resolve(configs) # resolve ${...} placeholders
|
||||
return configs
|
||||
|
||||
def get_optimizer(name: str, params: Parameter, **kwargs) -> Optimizer:
|
||||
if name == "adamw":
|
||||
return optim.AdamW(params=params, **kwargs)
|
||||
else:
|
||||
raise NotImplementedError(f"Not implemented optimizer: {name}")
|
||||
|
||||
def get_lr_scheduler(name: str, optimizer: Optimizer, **kwargs) -> LRScheduler:
|
||||
if name == "one_cycle":
|
||||
return lr_scheduler.OneCycleLR(
|
||||
optimizer,
|
||||
max_lr=kwargs["max_lr"],
|
||||
total_steps=kwargs["total_steps"],
|
||||
pct_start=kwargs["pct_start"],
|
||||
)
|
||||
elif name == "cosine_warmup":
|
||||
return get_scheduler(
|
||||
"cosine", optimizer,
|
||||
num_warmup_steps=kwargs["num_warmup_steps"],
|
||||
num_training_steps=kwargs["total_steps"],
|
||||
)
|
||||
elif name == "constant_warmup":
|
||||
return get_scheduler(
|
||||
"constant_with_warmup", optimizer,
|
||||
num_warmup_steps=kwargs["num_warmup_steps"],
|
||||
num_training_steps=kwargs["total_steps"],
|
||||
)
|
||||
elif name == "constant":
|
||||
return lr_scheduler.LambdaLR(optimizer=optimizer, lr_lambda=lambda _: 1)
|
||||
elif name == "linear_decay":
|
||||
return lr_scheduler.LambdaLR(
|
||||
optimizer=optimizer,
|
||||
lr_lambda=lambda epoch: max(0., 1. - epoch / kwargs["total_epochs"]),
|
||||
)
|
||||
else:
|
||||
raise NotImplementedError(f"Not implemented lr scheduler: {name}")
|
||||
|
||||
def save_experiment_params(
|
||||
args: Namespace,
|
||||
configs: DictConfig,
|
||||
save_dir: str
|
||||
) -> Dict[str, Any]:
|
||||
params = OmegaConf.merge(configs, {"args": {k: str(v) for k, v in vars(args).items()}})
|
||||
OmegaConf.save(params, os.path.join(save_dir, "params.yaml"))
|
||||
return dict(params)
|
||||
|
||||
|
||||
def save_model_architecture(model: Module, save_dir: str) -> None:
|
||||
num_buffers = sum(b.numel() for b in model.buffers())
|
||||
num_params = sum(p.numel() for p in model.parameters())
|
||||
num_trainable_params = sum(p.numel() for p in model.parameters() if p.requires_grad)
|
||||
message = f"Number of buffers: {num_buffers}\n" +\
|
||||
f"Number of trainable / all parameters: {num_trainable_params} / {num_params}\n\n" +\
|
||||
f"Model architecture:\n{model}"
|
||||
|
||||
with open(os.path.join(save_dir, "model.txt"), "w") as f:
|
||||
f.write(message)
|
||||
@@ -0,0 +1,20 @@
|
||||
from typing import *
|
||||
|
||||
from argparse import Namespace
|
||||
from collections import defaultdict
|
||||
from omegaconf import DictConfig, ListConfig
|
||||
from omegaconf.base import ContainerMetadata, Metadata
|
||||
from omegaconf.nodes import AnyNode
|
||||
|
||||
from torch import Tensor
|
||||
from torch.nn import Parameter, Module
|
||||
from torch.nn.parallel import DistributedDataParallel
|
||||
from torch.optim import Optimizer
|
||||
from torch.optim.lr_scheduler import LRScheduler
|
||||
from torch.utils.data import DataLoader
|
||||
|
||||
from accelerate.optimizer import AcceleratedOptimizer
|
||||
from accelerate.scheduler import AcceleratedScheduler
|
||||
from accelerate.data_loader import DataLoaderShard
|
||||
|
||||
|
||||
@@ -0,0 +1,191 @@
|
||||
import argparse
|
||||
import os
|
||||
import sys
|
||||
from glob import glob
|
||||
import time
|
||||
from typing import Any, Union
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import trimesh
|
||||
from huggingface_hub import snapshot_download
|
||||
from PIL import Image
|
||||
from accelerate.utils import set_seed
|
||||
# sys.path.append(os.path.abspath(os.path.join(os.path.dirname(__file__), "..", "partcrafter_src")))
|
||||
sys.path.append(os.path.abspath(os.path.join(os.path.dirname(__file__), "..")))
|
||||
|
||||
|
||||
|
||||
from partcrafter_src.utils.data_utils import get_colored_mesh_composition, scene_to_parts, load_surfaces
|
||||
from partcrafter_src.utils.render_utils import render_views_around_mesh, render_normal_views_around_mesh, make_grid_for_images_or_videos, export_renderings
|
||||
from partcrafter_src.pipelines.pipeline_partcrafter import PartCrafterPipeline
|
||||
from partcrafter_src.utils.image_utils import prepare_image
|
||||
from partcrafter_src.models.briarmbg import BriaRMBG
|
||||
|
||||
@torch.no_grad()
|
||||
def run_triposg(
|
||||
pipe: Any,
|
||||
image_input: Union[str, Image.Image],
|
||||
num_parts: int,
|
||||
rmbg_net: Any,
|
||||
seed: int,
|
||||
num_tokens: int = 1024,
|
||||
num_inference_steps: int = 50,
|
||||
guidance_scale: float = 7.0,
|
||||
max_num_expanded_coords: int = 1e9,
|
||||
use_flash_decoder: bool = False,
|
||||
rmbg: bool = False,
|
||||
dtype: torch.dtype = torch.float16,
|
||||
device: str = "cuda",
|
||||
) -> trimesh.Scene:
|
||||
|
||||
if rmbg:
|
||||
img_pil = prepare_image(image_input, bg_color=np.array([1.0, 1.0, 1.0]), rmbg_net=rmbg_net)
|
||||
else:
|
||||
img_pil = Image.open(image_input)
|
||||
start_time = time.time()
|
||||
outputs = pipe(
|
||||
image=[img_pil] * num_parts,
|
||||
attention_kwargs={"num_parts": num_parts},
|
||||
num_tokens=num_tokens,
|
||||
generator=torch.Generator(device=pipe.device).manual_seed(seed),
|
||||
num_inference_steps=num_inference_steps,
|
||||
guidance_scale=guidance_scale,
|
||||
max_num_expanded_coords=max_num_expanded_coords,
|
||||
use_flash_decoder=use_flash_decoder,
|
||||
).meshes
|
||||
end_time = time.time()
|
||||
print(f"Time elapsed: {end_time - start_time:.2f} seconds")
|
||||
for i in range(len(outputs)):
|
||||
if outputs[i] is None:
|
||||
# If the generated mesh is None (decoding error), use a dummy mesh
|
||||
outputs[i] = trimesh.Trimesh(vertices=[[0, 0, 0]], faces=[[0, 0, 0]])
|
||||
return outputs, img_pil
|
||||
|
||||
MAX_NUM_PARTS = 16
|
||||
|
||||
if __name__ == "__main__":
|
||||
device = "cuda"
|
||||
dtype = torch.float16
|
||||
|
||||
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--image_path", type=str, required=True)
|
||||
parser.add_argument("--num_parts", type=int, required=True, help="number of parts to generate")
|
||||
parser.add_argument("--output_dir", type=str, default="./results")
|
||||
parser.add_argument("--tag", type=str, default=None)
|
||||
parser.add_argument("--seed", type=int, default=13)
|
||||
parser.add_argument("--num_tokens", type=int, default=1024)
|
||||
parser.add_argument("--num_inference_steps", type=int, default=50)
|
||||
parser.add_argument("--guidance_scale", type=float, default=7.0)
|
||||
parser.add_argument("--max_num_expanded_coords", type=int, default=1e9)
|
||||
parser.add_argument("--use_flash_decoder", action="store_true")
|
||||
parser.add_argument("--rmbg", action="store_true")
|
||||
parser.add_argument("--render", action="store_true")
|
||||
parser.add_argument("--sampling_version", type=int, default=1, choices=[1, 2],
|
||||
help="Sampling version: 1=original, 2=fixed (per-batch with normalization)")
|
||||
args = parser.parse_args()
|
||||
|
||||
assert 1 <= args.num_parts <= MAX_NUM_PARTS, f"num_parts must be in [1, {MAX_NUM_PARTS}]"
|
||||
|
||||
# download pretrained weights
|
||||
partcrafter_weights_dir = "pretrained_weights/PartCrafter"
|
||||
rmbg_weights_dir = "pretrained_weights/RMBG-1.4"
|
||||
# ignore json file
|
||||
snapshot_download(repo_id="wgsxm/PartCrafter", local_dir=partcrafter_weights_dir, ignore_patterns=["*.json"])
|
||||
snapshot_download(repo_id="briaai/RMBG-1.4", local_dir=rmbg_weights_dir)
|
||||
|
||||
# init rmbg model for background removal
|
||||
rmbg_net = BriaRMBG.from_pretrained(rmbg_weights_dir).to(device)
|
||||
rmbg_net.eval()
|
||||
|
||||
# init tripoSG pipeline
|
||||
pipe: PartCrafterPipeline = PartCrafterPipeline.from_pretrained(partcrafter_weights_dir).to(device, dtype)
|
||||
|
||||
# DEBUG: Set sampling version
|
||||
print(f"🎛️ Setting sampling version to {args.sampling_version}")
|
||||
if hasattr(pipe.vae, 'set_sampling_version'):
|
||||
pipe.vae.set_sampling_version(args.sampling_version)
|
||||
else:
|
||||
print("⚠️ Warning: VAE doesn't have set_sampling_version method")
|
||||
|
||||
set_seed(args.seed)
|
||||
|
||||
# run inference
|
||||
outputs, processed_image = run_triposg(
|
||||
pipe,
|
||||
image_input=args.image_path,
|
||||
num_parts=args.num_parts,
|
||||
rmbg_net=rmbg_net,
|
||||
seed=args.seed,
|
||||
num_tokens=args.num_tokens,
|
||||
num_inference_steps=args.num_inference_steps,
|
||||
guidance_scale=args.guidance_scale,
|
||||
max_num_expanded_coords=args.max_num_expanded_coords,
|
||||
use_flash_decoder=args.use_flash_decoder,
|
||||
rmbg=args.rmbg,
|
||||
dtype=dtype,
|
||||
device=device,
|
||||
)
|
||||
|
||||
if not os.path.exists(args.output_dir):
|
||||
os.makedirs(args.output_dir)
|
||||
|
||||
if args.tag is None:
|
||||
args.tag = time.strftime("%Y%m%d_%H_%M_%S")
|
||||
|
||||
export_dir = os.path.join(args.output_dir, args.tag)
|
||||
os.makedirs(export_dir, exist_ok=True)
|
||||
|
||||
for i, mesh in enumerate(outputs):
|
||||
mesh.export(os.path.join(export_dir, f"part_{i:02}.glb"))
|
||||
|
||||
merged_mesh = get_colored_mesh_composition(outputs)
|
||||
merged_mesh.export(os.path.join(export_dir, "object.glb"))
|
||||
print(f"Generated {len(outputs)} parts and saved to {export_dir}")
|
||||
|
||||
if args.render:
|
||||
print("Start rendering...")
|
||||
num_views = 36
|
||||
radius = 4
|
||||
fps = 18
|
||||
rendered_images = render_views_around_mesh(
|
||||
merged_mesh,
|
||||
num_views=num_views,
|
||||
radius=radius,
|
||||
)
|
||||
rendered_normals = render_normal_views_around_mesh(
|
||||
merged_mesh,
|
||||
num_views=num_views,
|
||||
radius=radius,
|
||||
)
|
||||
rendered_grids = make_grid_for_images_or_videos(
|
||||
[
|
||||
[processed_image] * num_views,
|
||||
rendered_images,
|
||||
rendered_normals,
|
||||
],
|
||||
nrow=3
|
||||
)
|
||||
export_renderings(
|
||||
rendered_images,
|
||||
os.path.join(export_dir, "rendering.gif"),
|
||||
fps=fps,
|
||||
)
|
||||
export_renderings(
|
||||
rendered_normals,
|
||||
os.path.join(export_dir, "rendering_normal.gif"),
|
||||
fps=fps,
|
||||
)
|
||||
export_renderings(
|
||||
rendered_grids,
|
||||
os.path.join(export_dir, "rendering_grid.gif"),
|
||||
fps=fps,
|
||||
)
|
||||
|
||||
rendered_image, rendered_normal, rendered_grid = rendered_images[0], rendered_normals[0], rendered_grids[0]
|
||||
rendered_image.save(os.path.join(export_dir, "rendering.png"))
|
||||
rendered_normal.save(os.path.join(export_dir, "rendering_normal.png"))
|
||||
rendered_grid.save(os.path.join(export_dir, "rendering_grid.png"))
|
||||
print("Rendering done.")
|
||||
|
||||
@@ -0,0 +1,21 @@
|
||||
scikit-learn
|
||||
gpustat
|
||||
nvitop
|
||||
diffusers
|
||||
transformers
|
||||
einops
|
||||
huggingface_hub
|
||||
opencv-python
|
||||
trimesh
|
||||
omegaconf
|
||||
scikit-image
|
||||
numpy==1.26.4
|
||||
peft
|
||||
jaxtyping
|
||||
typeguard
|
||||
matplotlib
|
||||
imageio-ffmpeg
|
||||
pyrender
|
||||
deepspeed
|
||||
wandb[media]
|
||||
colormaps
|
||||
@@ -0,0 +1,3 @@
|
||||
pip install torch-cluster -f https://data.pyg.org/whl/torch-2.5.1+cu124.html
|
||||
pip install -r settings/requirements.txt
|
||||
sudo apt-get install libegl1 libegl1-mesa libgl1-mesa-dev -y # for rendering
|
||||
@@ -0,0 +1,70 @@
|
||||
#!/usr/bin/env python3
|
||||
|
||||
import sys
|
||||
import os
|
||||
sys.path.append('.')
|
||||
|
||||
import torch
|
||||
import numpy as np
|
||||
from partcrafter_src.models.autoencoders.autoencoder_kl_triposg import TripoSGVAEModel
|
||||
|
||||
def test_both_sampling_versions():
|
||||
"""Quick test of both sampling versions"""
|
||||
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
print(f"🚀 Testing on device: {device}")
|
||||
|
||||
# Create model
|
||||
model = TripoSGVAEModel(
|
||||
in_channels=3,
|
||||
latent_channels=64,
|
||||
num_attention_heads=8,
|
||||
width_encoder=512,
|
||||
width_decoder=1024,
|
||||
num_layers_encoder=8,
|
||||
num_layers_decoder=16,
|
||||
).to(device)
|
||||
|
||||
# Create realistic test data (simulating robot point cloud)
|
||||
batch_size = 2
|
||||
num_points = 8000
|
||||
|
||||
# Create test data with different scales (like real scenarios)
|
||||
test_data = torch.zeros(batch_size, num_points, 6, device=device)
|
||||
|
||||
# Batch 0: centered robot-like object
|
||||
test_data[0, :, :3] = torch.randn(num_points, 3, device=device) * 0.8
|
||||
test_data[0, :, 3:] = torch.randn(num_points, 3, device=device) * 0.1
|
||||
|
||||
# Batch 1: offset robot with different scale
|
||||
test_data[1, :, :3] = torch.randn(num_points, 3, device=device) * 1.5 + torch.tensor([2, 1, 0], device=device)
|
||||
test_data[1, :, 3:] = torch.randn(num_points, 3, device=device) * 0.2
|
||||
|
||||
print(f"📊 Test data shape: {test_data.shape}")
|
||||
print(f"📊 Coordinate ranges:")
|
||||
for b in range(batch_size):
|
||||
xyz = test_data[b, :, :3]
|
||||
print(f" Batch {b}: [{xyz.min():.2f}, {xyz.max():.2f}], std={xyz.std():.3f}")
|
||||
|
||||
# Compare both versions
|
||||
sampled_v1, sampled_v2 = model.compare_sampling_versions(test_data, num_tokens=2048, seed=42)
|
||||
|
||||
print(f"\n🎯 FINAL RECOMMENDATION:")
|
||||
v1_zeros = sum([(sampled_v1[b].abs().sum(-1) < 1e-6).sum().item() for b in range(batch_size)])
|
||||
v2_zeros = sum([(sampled_v2[b].abs().sum(-1) < 1e-6).sum().item() for b in range(batch_size)])
|
||||
|
||||
if v1_zeros > v2_zeros:
|
||||
print(f"✅ Version 2 is BETTER (fewer zero artifacts: {v2_zeros} vs {v1_zeros})")
|
||||
recommended_version = 2
|
||||
elif v2_zeros > v1_zeros:
|
||||
print(f"❌ Version 1 is better (fewer zero artifacts: {v1_zeros} vs {v2_zeros})")
|
||||
recommended_version = 1
|
||||
else:
|
||||
print(f"⚖️ Both versions have similar zero padding: {v1_zeros}")
|
||||
recommended_version = 2 # Default to fixed version
|
||||
|
||||
return recommended_version
|
||||
|
||||
if __name__ == "__main__":
|
||||
recommended = test_both_sampling_versions()
|
||||
print(f"\n🎯 Use version {recommended} for your robot inference!")
|
||||
@@ -0,0 +1,337 @@
|
||||
{
|
||||
"id": "8fb4df3a-d3bc-4b42-95f2-434fb48a8992",
|
||||
"revision": 0,
|
||||
"last_node_id": 9,
|
||||
"last_link_id": 7,
|
||||
"nodes": [
|
||||
{
|
||||
"id": 1,
|
||||
"type": "[Comfy3D] Load PartCrafter Pipeline",
|
||||
"pos": [
|
||||
2233.307861328125,
|
||||
1132.6119384765625
|
||||
],
|
||||
"size": [
|
||||
197.09921264648438,
|
||||
26
|
||||
],
|
||||
"flags": {},
|
||||
"order": 0,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "partcrafter_pipe",
|
||||
"type": "DIFFUSERS_PIPE",
|
||||
"links": [
|
||||
1
|
||||
]
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "[Comfy3D] Load PartCrafter Pipeline"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 8,
|
||||
"type": "[Comfy3D] Preview 3DMesh",
|
||||
"pos": [
|
||||
3333.187744140625,
|
||||
1183.9188232421875
|
||||
],
|
||||
"size": [
|
||||
600,
|
||||
500
|
||||
],
|
||||
"flags": {},
|
||||
"order": 6,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "mesh_file_path",
|
||||
"type": "STRING",
|
||||
"widget": {
|
||||
"name": "mesh_file_path"
|
||||
},
|
||||
"link": 6
|
||||
}
|
||||
],
|
||||
"outputs": [],
|
||||
"properties": {
|
||||
"Node name for S&R": "[Comfy3D] Preview 3DMesh"
|
||||
},
|
||||
"widgets_values": [
|
||||
"",
|
||||
null
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 3,
|
||||
"type": "LoadImage",
|
||||
"pos": [
|
||||
2161.17333984375,
|
||||
1232.0296630859375
|
||||
],
|
||||
"size": [
|
||||
353.18182373046875,
|
||||
489.7575378417969
|
||||
],
|
||||
"flags": {},
|
||||
"order": 1,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"slot_index": 0,
|
||||
"links": [
|
||||
2
|
||||
]
|
||||
},
|
||||
{
|
||||
"name": "MASK",
|
||||
"type": "MASK",
|
||||
"slot_index": 1,
|
||||
"links": []
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadImage"
|
||||
},
|
||||
"widgets_values": [
|
||||
"robot.png",
|
||||
"image"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 2,
|
||||
"type": "[Comfy3D] PartCrafter Generate",
|
||||
"pos": [
|
||||
2550.86669921875,
|
||||
1193.7396240234375
|
||||
],
|
||||
"size": [
|
||||
318.76953125,
|
||||
314
|
||||
],
|
||||
"flags": {},
|
||||
"order": 2,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "partcrafter_pipe",
|
||||
"type": "DIFFUSERS_PIPE",
|
||||
"link": 1
|
||||
},
|
||||
{
|
||||
"name": "image",
|
||||
"type": "IMAGE",
|
||||
"link": 2
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "parts_zip_path",
|
||||
"type": "STRING",
|
||||
"links": [
|
||||
7
|
||||
]
|
||||
},
|
||||
{
|
||||
"name": "merged_mesh",
|
||||
"type": "MESH",
|
||||
"links": [
|
||||
5
|
||||
]
|
||||
},
|
||||
{
|
||||
"name": "processed_image",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
3
|
||||
]
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "[Comfy3D] PartCrafter Generate"
|
||||
},
|
||||
"widgets_values": [
|
||||
4,
|
||||
228764490511818,
|
||||
"randomize",
|
||||
1024,
|
||||
50,
|
||||
7,
|
||||
1000000000,
|
||||
false,
|
||||
false,
|
||||
2
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 9,
|
||||
"type": "PreviewAny",
|
||||
"pos": [
|
||||
2912.02490234375,
|
||||
1048.1806640625
|
||||
],
|
||||
"size": [
|
||||
350.2099609375,
|
||||
88
|
||||
],
|
||||
"flags": {},
|
||||
"order": 3,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "source",
|
||||
"type": "*",
|
||||
"link": 7
|
||||
}
|
||||
],
|
||||
"outputs": [],
|
||||
"properties": {
|
||||
"Node name for S&R": "PreviewAny"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 7,
|
||||
"type": "[Comfy3D] Save 3D Mesh",
|
||||
"pos": [
|
||||
2933.991943359375,
|
||||
1229.566162109375
|
||||
],
|
||||
"size": [
|
||||
315,
|
||||
58
|
||||
],
|
||||
"flags": {},
|
||||
"order": 4,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "mesh",
|
||||
"type": "MESH",
|
||||
"link": 5
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "save_path",
|
||||
"type": "STRING",
|
||||
"slot_index": 0,
|
||||
"links": [
|
||||
6
|
||||
]
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "[Comfy3D] Save 3D Mesh"
|
||||
},
|
||||
"widgets_values": [
|
||||
"PartCrafter_Test/mesh.glb"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 5,
|
||||
"type": "PreviewImage",
|
||||
"pos": [
|
||||
2928.69384765625,
|
||||
1368.6041259765625
|
||||
],
|
||||
"size": [
|
||||
321.450439453125,
|
||||
394.6763916015625
|
||||
],
|
||||
"flags": {},
|
||||
"order": 5,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 3
|
||||
}
|
||||
],
|
||||
"outputs": [],
|
||||
"properties": {
|
||||
"Node name for S&R": "PreviewImage"
|
||||
},
|
||||
"widgets_values": []
|
||||
}
|
||||
],
|
||||
"links": [
|
||||
[
|
||||
1,
|
||||
1,
|
||||
0,
|
||||
2,
|
||||
0,
|
||||
"DIFFUSERS_PIPE"
|
||||
],
|
||||
[
|
||||
2,
|
||||
3,
|
||||
0,
|
||||
2,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
3,
|
||||
2,
|
||||
2,
|
||||
5,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
5,
|
||||
2,
|
||||
1,
|
||||
7,
|
||||
0,
|
||||
"MESH"
|
||||
],
|
||||
[
|
||||
6,
|
||||
7,
|
||||
0,
|
||||
8,
|
||||
0,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
7,
|
||||
2,
|
||||
0,
|
||||
9,
|
||||
0,
|
||||
"*"
|
||||
]
|
||||
],
|
||||
"groups": [],
|
||||
"config": {},
|
||||
"extra": {
|
||||
"ds": {
|
||||
"scale": 0.9070294784580498,
|
||||
"offset": [
|
||||
-2140.713805878563,
|
||||
-975.661308705606
|
||||
]
|
||||
},
|
||||
"node_versions": {
|
||||
"ComfyUI-3D-Pack": "aedee80e370321bd78221b086445fe8a5f2f8906",
|
||||
"comfy-core": "0.3.44"
|
||||
},
|
||||
"frontendVersion": "1.23.4",
|
||||
"VHS_latentpreview": false,
|
||||
"VHS_latentpreviewrate": 0,
|
||||
"VHS_MetadataImage": true,
|
||||
"VHS_KeepIntermediate": true
|
||||
},
|
||||
"version": 0.4
|
||||
}
|
||||
@@ -124,6 +124,10 @@ from Gen_3D_Modules.Hunyuan3D_2_1 import (
|
||||
)
|
||||
from Gen_3D_Modules.Hunyuan3D_2_1.hy3dpaint.utils.torchvision_fix import apply_fix
|
||||
apply_fix()
|
||||
from Gen_3D_Modules.PartCrafter.partcrafter_src.pipelines.pipeline_partcrafter import PartCrafterPipeline
|
||||
from Gen_3D_Modules.PartCrafter.partcrafter_src.utils.data_utils import get_colored_mesh_composition
|
||||
from Gen_3D_Modules.PartCrafter.partcrafter_src.utils.image_utils import prepare_image
|
||||
import zipfile
|
||||
|
||||
|
||||
os.environ['SPCONV_ALGO'] = 'native'
|
||||
@@ -5572,3 +5576,214 @@ class Hunyuan3D_21_TexGen:
|
||||
except:
|
||||
pass
|
||||
|
||||
|
||||
|
||||
|
||||
class Load_PartCrafter_Pipeline:
|
||||
"""Load PartCrafter Pipeline"""
|
||||
|
||||
CATEGORY = "Comfy3D/Algorithm/PartCrafter"
|
||||
RETURN_TYPES = ("DIFFUSERS_PIPE",)
|
||||
RETURN_NAMES = ("partcrafter_pipe",)
|
||||
FUNCTION = "load"
|
||||
|
||||
_REPO_ID = "wgsxm/PartCrafter"
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {},
|
||||
}
|
||||
|
||||
@staticmethod
|
||||
def _ensure_weights():
|
||||
safe_repo_name = Load_PartCrafter_Pipeline._REPO_ID.replace("/", "_")
|
||||
base_dir = os.path.join(CKPT_DIFFUSERS_PATH, Load_PartCrafter_Pipeline._REPO_ID)
|
||||
|
||||
required_files = [
|
||||
"diffusion_pytorch_model.safetensors",
|
||||
"diffusion_pytorch_model.bin",
|
||||
]
|
||||
|
||||
files_missing = []
|
||||
|
||||
for file_path in required_files:
|
||||
full_file_path = os.path.join(base_dir, file_path)
|
||||
if not os.path.exists(full_file_path):
|
||||
files_missing.append(file_path)
|
||||
|
||||
if files_missing or not os.path.exists(base_dir):
|
||||
print(f"Loading PartCrafter from {Load_PartCrafter_Pipeline._REPO_ID}...")
|
||||
print(f"Missing files: {len(files_missing)}")
|
||||
snapshot_download(
|
||||
repo_id=Load_PartCrafter_Pipeline._REPO_ID,
|
||||
repo_type="model",
|
||||
local_dir=base_dir,
|
||||
resume_download=True,
|
||||
ignore_patterns=HF_DOWNLOAD_IGNORE,
|
||||
)
|
||||
print(f"PartCrafter loaded successfully")
|
||||
else:
|
||||
print(f"PartCrafter weights already loaded")
|
||||
|
||||
return base_dir
|
||||
|
||||
def load(self):
|
||||
base_dir = self._ensure_weights()
|
||||
|
||||
pipeline = PartCrafterPipeline.from_pretrained(base_dir).to(DEVICE, WEIGHT_DTYPE)
|
||||
|
||||
print(f"PartCrafter pipeline loaded")
|
||||
return (pipeline,)
|
||||
|
||||
class PartCrafter_Generate:
|
||||
"""PartCrafter Generation"""
|
||||
|
||||
CATEGORY = "Comfy3D/Algorithm/PartCrafter"
|
||||
RETURN_TYPES = ("STRING", "MESH", "IMAGE")
|
||||
RETURN_NAMES = ("parts_zip_path", "merged_mesh", "processed_image")
|
||||
FUNCTION = "generate"
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"partcrafter_pipe": ("DIFFUSERS_PIPE",),
|
||||
"image": ("IMAGE",),
|
||||
"num_parts": ("INT", {"default": 4, "min": 1, "max": 16}),
|
||||
"seed": ("INT", {"default": 1234, "min": 0, "max": 0xffffffffffffffff}),
|
||||
"num_tokens": ("INT", {"default": 1024, "min": 256, "max": 2048}),
|
||||
"num_inference_steps": ("INT", {"default": 50, "min": 1, "max": 100}),
|
||||
"guidance_scale": ("FLOAT", {"default": 7.0, "min": 0.0, "step": 0.1}),
|
||||
"max_num_expanded_coords": ("INT", {"default": 1000000000, "min": 1000, "max": 10000000000}),
|
||||
"use_flash_decoder": ("BOOLEAN", {"default": False}),
|
||||
"remove_background": ("BOOLEAN", {"default": True}),
|
||||
"sampling_version": ("INT", {"default": 1, "min": 1, "max": 2}),
|
||||
}
|
||||
}
|
||||
|
||||
@torch.no_grad()
|
||||
def generate(self, partcrafter_pipe, image, num_parts, seed, num_tokens, num_inference_steps,
|
||||
guidance_scale, max_num_expanded_coords, use_flash_decoder, remove_background, sampling_version):
|
||||
|
||||
# Convert image
|
||||
pil_image = torch_imgs_to_pils(image)[0]
|
||||
|
||||
# Remove background if needed
|
||||
if remove_background:
|
||||
rmbg_worker = BackgroundRemover_2_1()
|
||||
if pil_image.mode == "RGBA":
|
||||
pil_image = pil_image.convert('RGB')
|
||||
pil_image = rmbg_worker(pil_image)
|
||||
del rmbg_worker
|
||||
|
||||
# Set sampling version
|
||||
if hasattr(partcrafter_pipe.vae, 'set_sampling_version'):
|
||||
partcrafter_pipe.vae.set_sampling_version(sampling_version)
|
||||
|
||||
# Generation
|
||||
generator = torch.Generator(device=partcrafter_pipe.device)
|
||||
generator = generator.manual_seed(int(seed))
|
||||
|
||||
outputs = partcrafter_pipe(
|
||||
image=[pil_image] * num_parts,
|
||||
attention_kwargs={"num_parts": num_parts},
|
||||
num_tokens=num_tokens,
|
||||
generator=generator,
|
||||
num_inference_steps=num_inference_steps,
|
||||
guidance_scale=guidance_scale,
|
||||
max_num_expanded_coords=max_num_expanded_coords,
|
||||
use_flash_decoder=use_flash_decoder,
|
||||
).meshes
|
||||
|
||||
# Process results
|
||||
for i in range(len(outputs)):
|
||||
if outputs[i] is None:
|
||||
# If mesh is None (decoding error), use dummy mesh
|
||||
outputs[i] = trimesh.Trimesh(vertices=[[0, 0, 0]], faces=[[0, 0, 0]])
|
||||
|
||||
# Create merged mesh
|
||||
merged_mesh_trimesh = get_colored_mesh_composition(outputs)
|
||||
|
||||
# Debug logging
|
||||
print(f"Merged mesh type: {type(merged_mesh_trimesh)}")
|
||||
print(f"Merged mesh attributes: {dir(merged_mesh_trimesh)}")
|
||||
if hasattr(merged_mesh_trimesh, 'geometry'):
|
||||
print(f"Scene geometry keys: {list(merged_mesh_trimesh.geometry.keys())}")
|
||||
|
||||
# Create ZIP with individual parts
|
||||
parts_output_dir = "output/partcrafter_parts"
|
||||
os.makedirs(parts_output_dir, exist_ok=True)
|
||||
|
||||
zip_path = os.path.join(parts_output_dir, f"parts_seed_{seed}.zip")
|
||||
|
||||
with zipfile.ZipFile(zip_path, 'w', zipfile.ZIP_DEFLATED) as zipf:
|
||||
for i, part in enumerate(outputs):
|
||||
print(f"Part {i} type: {type(part)}")
|
||||
if part is not None:
|
||||
# Save part as GLB file
|
||||
part_path = os.path.join(parts_output_dir, f"part_{i:02d}.glb")
|
||||
part.export(part_path)
|
||||
|
||||
# Add to ZIP
|
||||
zipf.write(part_path, f"part_{i:02d}.glb")
|
||||
|
||||
# Clean up temporary file
|
||||
try:
|
||||
os.remove(part_path)
|
||||
except:
|
||||
pass
|
||||
|
||||
print(f"Created parts ZIP: {zip_path}")
|
||||
|
||||
# Handle Scene vs Mesh for merged result
|
||||
if isinstance(merged_mesh_trimesh, trimesh.Scene):
|
||||
print("Merged result is Scene, combining all geometries")
|
||||
if merged_mesh_trimesh.geometry:
|
||||
# Combine all geometries into one mesh
|
||||
all_meshes = []
|
||||
for geom_name in merged_mesh_trimesh.geometry:
|
||||
geom = merged_mesh_trimesh.geometry[geom_name]
|
||||
print(f"Geometry {geom_name}: {type(geom)}, vertices: {len(geom.vertices)}, faces: {len(geom.faces)}")
|
||||
all_meshes.append(geom)
|
||||
|
||||
# Combine all meshes into one
|
||||
if len(all_meshes) > 1:
|
||||
combined_mesh = trimesh.util.concatenate(all_meshes)
|
||||
print(f"Combined mesh: vertices: {len(combined_mesh.vertices)}, faces: {len(combined_mesh.faces)}")
|
||||
else:
|
||||
combined_mesh = all_meshes[0]
|
||||
|
||||
merged_mesh = Mesh.load_trimesh(given_mesh=combined_mesh)
|
||||
else:
|
||||
print("Scene has no geometry, creating dummy mesh")
|
||||
# Create a dummy mesh if scene is empty
|
||||
dummy_trimesh = trimesh.Trimesh(vertices=[[0, 0, 0]], faces=[[0, 0, 0]])
|
||||
merged_mesh = Mesh.load_trimesh(given_mesh=dummy_trimesh)
|
||||
else:
|
||||
print("Merged result is Mesh, loading directly")
|
||||
merged_mesh = Mesh.load_trimesh(given_mesh=merged_mesh_trimesh)
|
||||
|
||||
merged_mesh.auto_normal()
|
||||
|
||||
# Save debug merged result
|
||||
try:
|
||||
debug_dir = "output/partcrafter_debug"
|
||||
os.makedirs(debug_dir, exist_ok=True)
|
||||
|
||||
# Save merged result for debugging
|
||||
if isinstance(merged_mesh_trimesh, trimesh.Scene):
|
||||
merged_mesh_trimesh.export(os.path.join(debug_dir, f"merged_scene_seed_{seed}.glb"))
|
||||
else:
|
||||
merged_mesh_trimesh.export(os.path.join(debug_dir, f"merged_mesh_seed_{seed}.obj"))
|
||||
|
||||
print(f"Debug merged file saved to {debug_dir}")
|
||||
except Exception as e:
|
||||
print(f"Failed to save debug files: {e}")
|
||||
|
||||
# Processed image
|
||||
processed_image_tensor = pils_to_torch_imgs([pil_image])
|
||||
|
||||
print(f"Generated {len(outputs)} parts")
|
||||
|
||||
return (zip_path, merged_mesh, processed_image_tensor)
|
||||
|
||||
Reference in New Issue
Block a user