update comfyui
This commit is contained in:
 bubbliiiing
@@ -0,0 +1,58 @@
|
||||
# ComfyUI EasyAnimate
|
||||
Easily use EasyAnimate inside ComfyUI!
|
||||
|
||||
[](https://arxiv.org/abs/2405.18991)
|
||||
[](https://easyanimate.github.io/)
|
||||
[](https://modelscope.cn/studios/PAI/EasyAnimate/summary)
|
||||
[](https://huggingface.co/spaces/alibaba-pai/EasyAnimate)
|
||||
|
||||
- [Installation](#1-installation)
|
||||
- [Node types](#node-types)
|
||||
- [Example workflows](#example-workflows)
|
||||
- [Image to video](#image-to-video)
|
||||
- [Image to video generation (high FPS w/ frame interpolation)](#image-to-video-generation-high-fps-w-frame-interpolation)
|
||||
|
||||
## 1. Installation
|
||||
|
||||
### Option 1: Install via ComfyUI Manager
|
||||
TBD
|
||||
|
||||
### Option 2: Install manually
|
||||
```
|
||||
cd ComfyUI/custom_nodes/
|
||||
git clone https://github.com/aigc-apps/EasyAnimate.git
|
||||
cd ComfyUI-Stable-Video-Diffusion/
|
||||
python install.py
|
||||
```
|
||||
|
||||
### 2. Download models into `ComfyUI/models/EasyAnimate/`
|
||||
EasyAnimateV3:
|
||||
| Name | Type | Storage Space | Url | Hugging Face | Description |
|
||||
|--|--|--|--|--|--|
|
||||
| EasyAnimateV3-XL-2-InP-512x512.tar | EasyAnimateV3 | 18.2GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/Diffusion_Transformer/EasyAnimateV3-XL-2-InP-512x512.tar) | [🤗Link](https://huggingface.co/alibaba-pai/EasyAnimateV3-XL-2-InP-512x512) | EasyAnimateV3 official weights for 512x512 text and image to video resolution. Training with 144 frames and fps 24 |
|
||||
| EasyAnimateV3-XL-2-InP-768x768.tar | EasyAnimateV3 | 18.2GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/Diffusion_Transformer/EasyAnimateV3-XL-2-InP-768x768.tar) | [🤗Link](https://huggingface.co/alibaba-pai/EasyAnimateV3-XL-2-InP-768x768) | EasyAnimateV3 official weights for 768x768 text and image to video resolution. Training with 144 frames and fps 24 |
|
||||
| EasyAnimateV3-XL-2-InP-960x960.tar | EasyAnimateV3 | 18.2GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/Diffusion_Transformer/EasyAnimateV3-XL-2-InP-960x960.tar) | [🤗Link](https://huggingface.co/alibaba-pai/EasyAnimateV3-XL-2-InP-960x960) | EasyAnimateV3 official weights for 960x960 text and image to video resolution. Training with 144 frames and fps 24 |
|
||||
|
||||
## Node types
|
||||
- **LoadEasyAnimateModel**
|
||||
- Loads the EasyAnimate model
|
||||
- **TextBox**
|
||||
- Write the prompt for EasyAnimate model
|
||||
- **EasyAnimateI2VSampler**
|
||||
- EasyAnimate Sampler for Image to Video
|
||||
- **EasyAnimateT2VSampler**
|
||||
- EasyAnimate Sampler for Text to Video
|
||||
|
||||
## Example workflows
|
||||
|
||||
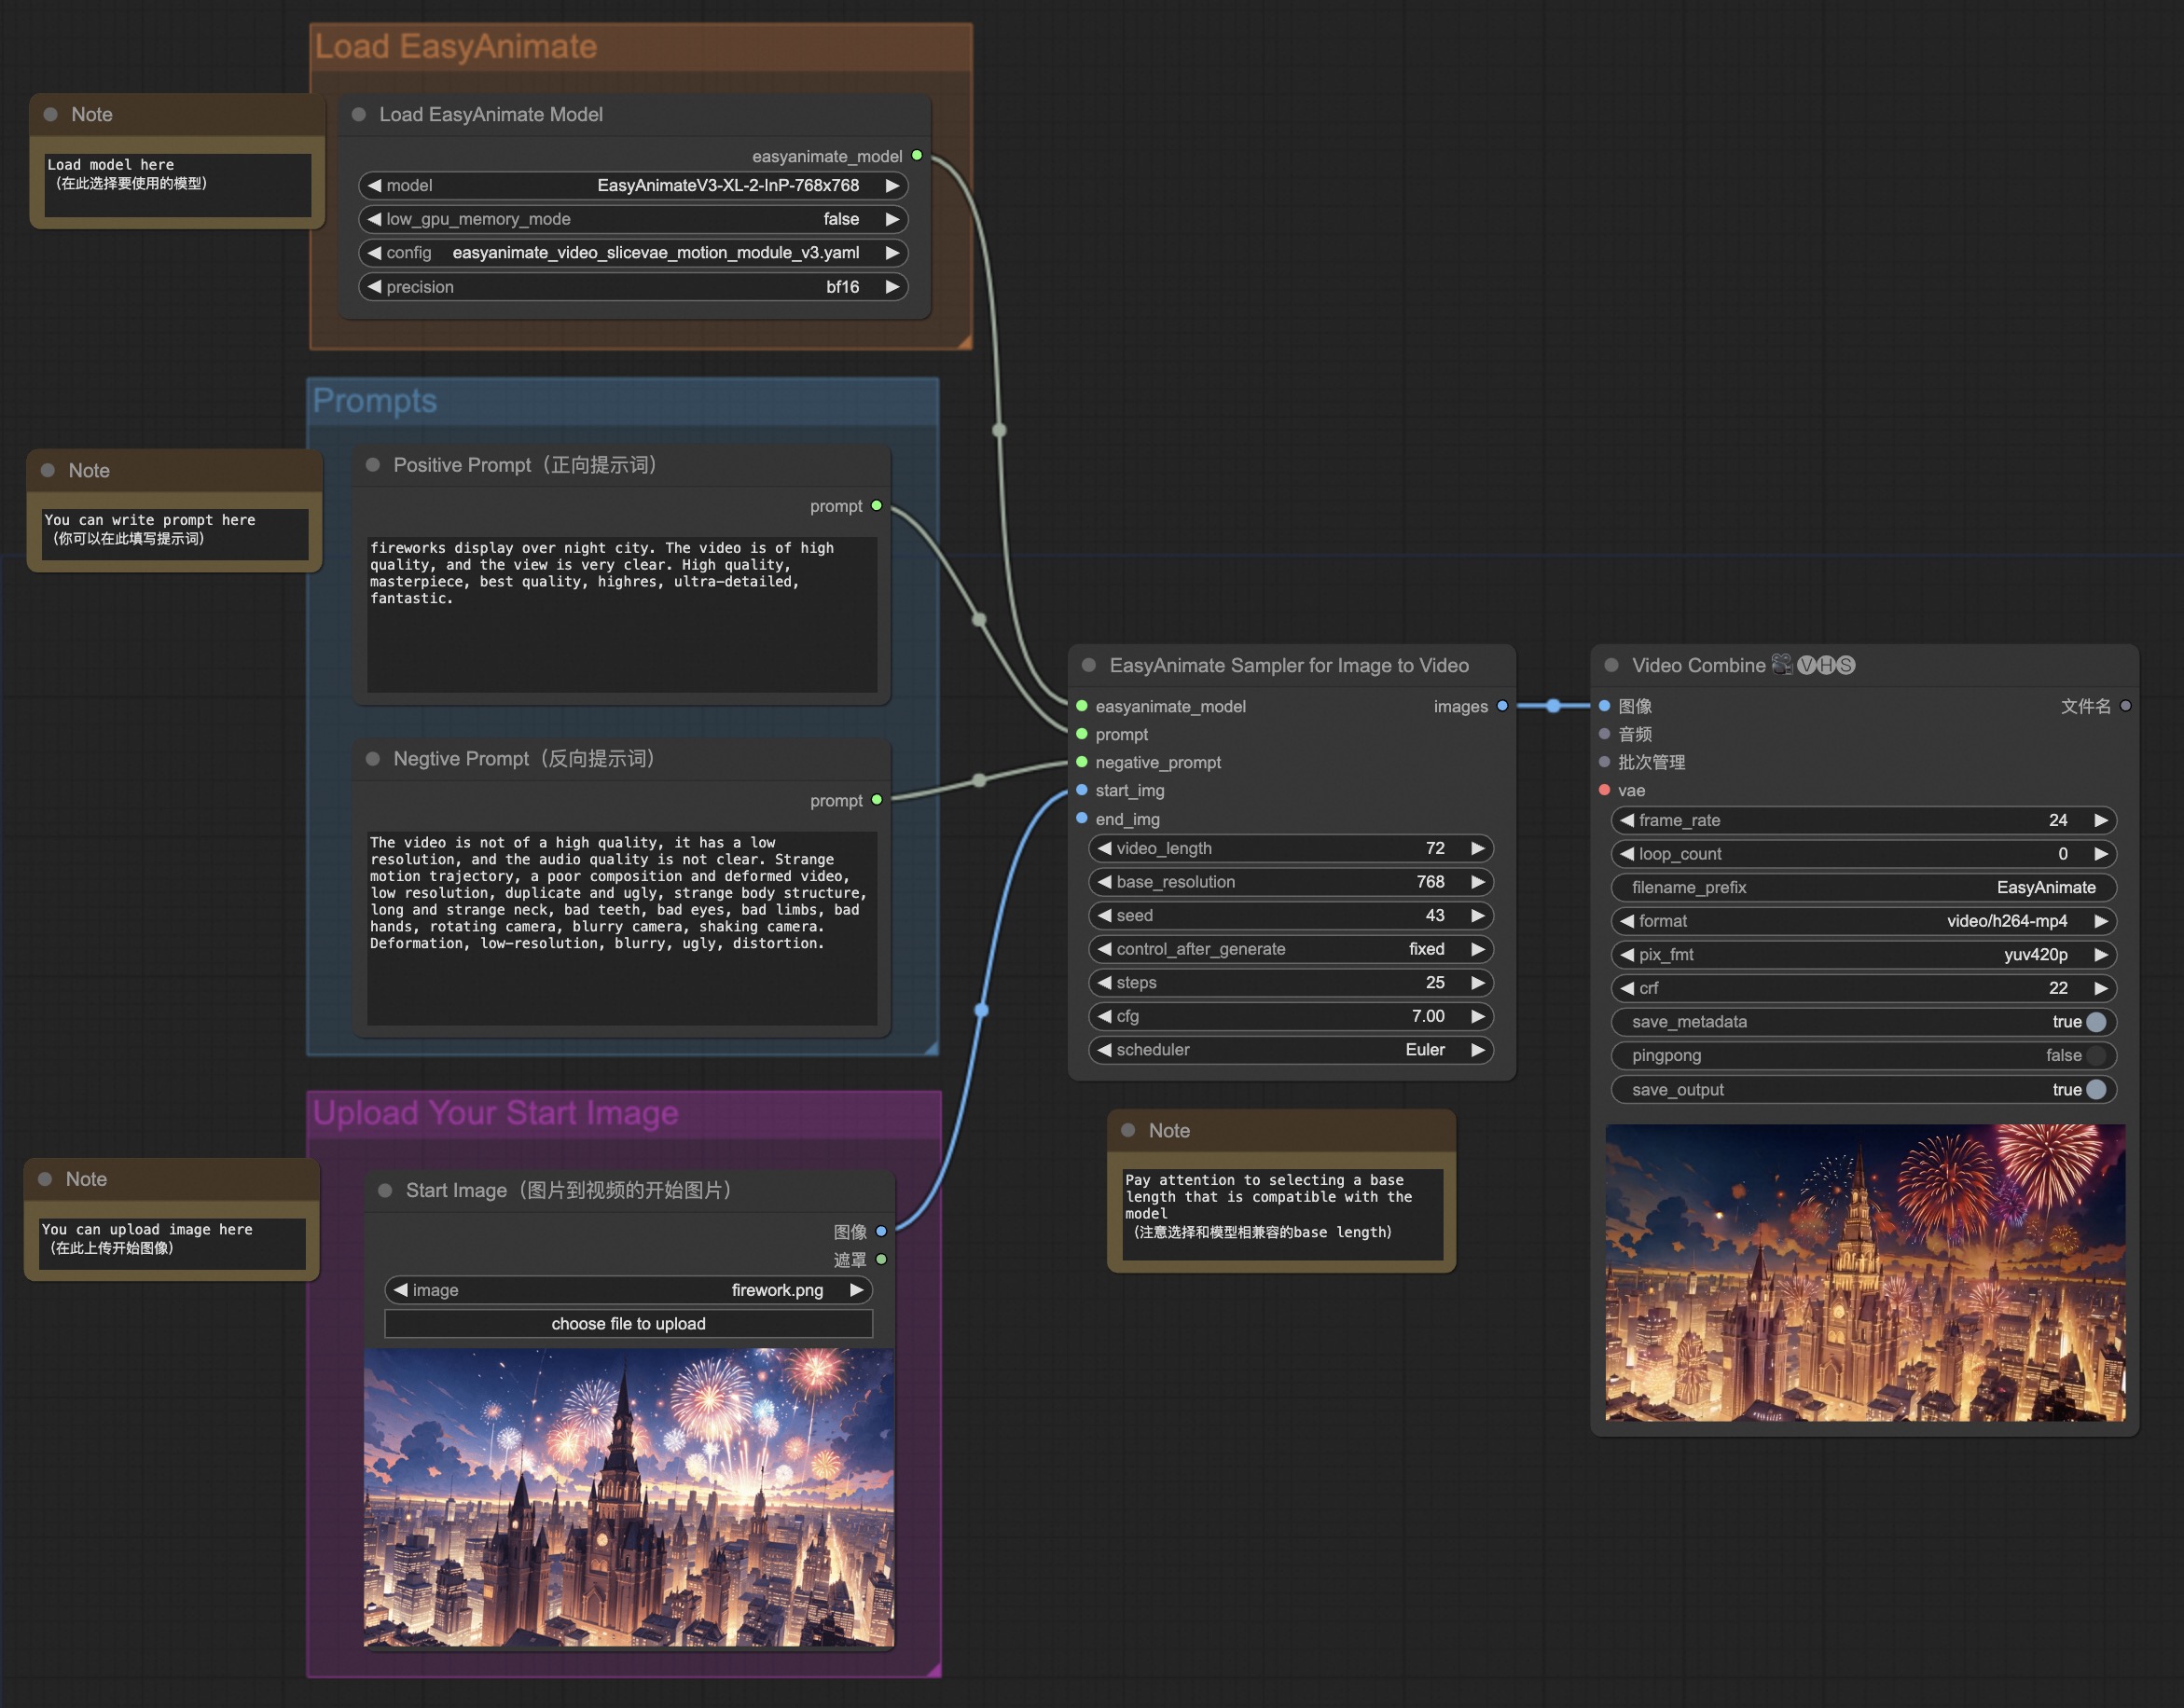
### Image to video
|
||||
Our ui is shown as follow:
|
||||
|
||||
|
||||
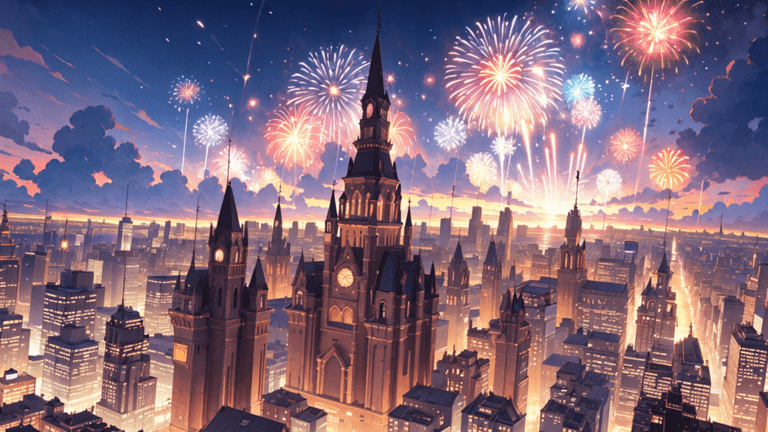
You can run the demo using following photo:
|
||||
|
||||
|
||||
|
||||
### Image to video generation (high FPS w/ frame interpolation)
|
||||
Our ui is shown as follow:
|
||||

|
||||
@@ -0,0 +1,432 @@
|
||||
import gc
|
||||
import os
|
||||
|
||||
import torch
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
from diffusers import (AutoencoderKL, DDIMScheduler,
|
||||
DPMSolverMultistepScheduler,
|
||||
EulerAncestralDiscreteScheduler, EulerDiscreteScheduler,
|
||||
PNDMScheduler)
|
||||
from einops import rearrange
|
||||
from omegaconf import OmegaConf
|
||||
from transformers import CLIPImageProcessor, CLIPVisionModelWithProjection
|
||||
|
||||
import comfy.model_management as mm
|
||||
import folder_paths
|
||||
from comfy.utils import ProgressBar, load_torch_file
|
||||
|
||||
from ..models.autoencoder_magvit import AutoencoderKLMagvit
|
||||
from ..models.transformer3d import Transformer3DModel
|
||||
from ..pipeline.pipeline_easyanimate_inpaint import EasyAnimateInpaintPipeline
|
||||
from ..utils.utils import get_image_to_video_latent
|
||||
from ..data.bucket_sampler import ASPECT_RATIO_512, get_closest_ratio
|
||||
|
||||
# Compatible with Alibaba EAS for quick launch
|
||||
eas_cache_dir = '/stable-diffusion-cache/models'
|
||||
# The directory of the easyanimate
|
||||
script_directory = os.path.dirname(os.path.dirname(os.path.dirname(os.path.abspath(__file__))))
|
||||
|
||||
def tensor2pil(image):
|
||||
return Image.fromarray(np.clip(255. * image.cpu().numpy(), 0, 255).astype(np.uint8))
|
||||
|
||||
def numpy2pil(image):
|
||||
return Image.fromarray(np.clip(255. * image, 0, 255).astype(np.uint8))
|
||||
|
||||
def to_pil(image):
|
||||
if isinstance(image, Image.Image):
|
||||
return image
|
||||
if isinstance(image, torch.Tensor):
|
||||
return tensor2pil(image)
|
||||
if isinstance(image, np.ndarray):
|
||||
return numpy2pil(image)
|
||||
raise ValueError(f"Cannot convert {type(image)} to PIL.Image")
|
||||
|
||||
class LoadEasyAnimateModel:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"model": (
|
||||
[
|
||||
'EasyAnimateV3-XL-2-InP-512x512',
|
||||
'EasyAnimateV3-XL-2-InP-768x768',
|
||||
'EasyAnimateV3-XL-2-InP-960x960'
|
||||
],
|
||||
{
|
||||
"default": 'EasyAnimateV3-XL-2-InP-768x768',
|
||||
}
|
||||
),
|
||||
"low_gpu_memory_mode":(
|
||||
[False, True],
|
||||
{
|
||||
"default": False,
|
||||
}
|
||||
),
|
||||
"config": (
|
||||
[
|
||||
"easyanimate_video_slicevae_motion_module_v3.yaml",
|
||||
],
|
||||
{
|
||||
"default": "easyanimate_video_slicevae_motion_module_v3.yaml",
|
||||
}
|
||||
),
|
||||
"precision": (
|
||||
['fp16', 'bf16'],
|
||||
{
|
||||
"default": 'bf16'
|
||||
}
|
||||
),
|
||||
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("EASYANIMATESMODEL",)
|
||||
RETURN_NAMES = ("easyanimate_model",)
|
||||
FUNCTION = "loadmodel"
|
||||
CATEGORY = "EasyAnimateWrapper"
|
||||
|
||||
def loadmodel(self, low_gpu_memory_mode, model, precision, config):
|
||||
# Init weight_dtype and device
|
||||
device = mm.get_torch_device()
|
||||
offload_device = mm.unet_offload_device()
|
||||
weight_dtype = {"bf16": torch.bfloat16, "fp16": torch.float16, "fp32": torch.float32}[precision]
|
||||
|
||||
# Init processbar
|
||||
pbar = ProgressBar(4)
|
||||
|
||||
# Load config
|
||||
config_path = f"{script_directory}/config/{config}"
|
||||
config = OmegaConf.load(config_path)
|
||||
|
||||
# Detect model is existing or not
|
||||
model_path = os.path.join(folder_paths.models_dir, "EasyAnimate", model)
|
||||
|
||||
if not os.path.exists(model_path):
|
||||
if os.path.exists(eas_cache_dir):
|
||||
model_path = os.path.join(eas_cache_dir, 'EasyAnimate', model)
|
||||
else:
|
||||
print(f"Please download easyanimate model to: {model_path}")
|
||||
|
||||
# Load vae
|
||||
if OmegaConf.to_container(config['vae_kwargs'])['enable_magvit']:
|
||||
Choosen_AutoencoderKL = AutoencoderKLMagvit
|
||||
else:
|
||||
Choosen_AutoencoderKL = AutoencoderKL
|
||||
print("Load Vae.")
|
||||
vae = Choosen_AutoencoderKL.from_pretrained(
|
||||
model_path,
|
||||
subfolder="vae",
|
||||
).to(weight_dtype)
|
||||
# Update pbar
|
||||
pbar.update(1)
|
||||
|
||||
# Load Sampler
|
||||
print("Load Sampler.")
|
||||
scheduler = EulerDiscreteScheduler.from_pretrained(model_path, subfolder= 'scheduler')
|
||||
# Update pbar
|
||||
pbar.update(1)
|
||||
|
||||
# Load Transformer
|
||||
print("Load Transformer.")
|
||||
transformer = Transformer3DModel.from_pretrained(
|
||||
model_path,
|
||||
subfolder= 'transformer',
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs'])
|
||||
).to(weight_dtype).eval()
|
||||
# Update pbar
|
||||
pbar.update(1)
|
||||
|
||||
# Load Transformer
|
||||
if transformer.config.in_channels == 12:
|
||||
clip_image_encoder = CLIPVisionModelWithProjection.from_pretrained(
|
||||
model_path, subfolder="image_encoder"
|
||||
).to(device, weight_dtype)
|
||||
clip_image_processor = CLIPImageProcessor.from_pretrained(
|
||||
model_path, subfolder="image_encoder"
|
||||
)
|
||||
else:
|
||||
clip_image_encoder = None
|
||||
clip_image_processor = None
|
||||
# Update pbar
|
||||
pbar.update(1)
|
||||
|
||||
pipeline = EasyAnimateInpaintPipeline.from_pretrained(
|
||||
model_path,
|
||||
transformer=transformer,
|
||||
scheduler=scheduler,
|
||||
vae=vae,
|
||||
torch_dtype=weight_dtype,
|
||||
clip_image_encoder=clip_image_encoder,
|
||||
clip_image_processor=clip_image_processor,
|
||||
)
|
||||
|
||||
if low_gpu_memory_mode:
|
||||
pipeline.enable_sequential_cpu_offload()
|
||||
else:
|
||||
pipeline.enable_model_cpu_offload()
|
||||
|
||||
easyanimate_model = {
|
||||
'pipeline': pipeline,
|
||||
'dtype': weight_dtype,
|
||||
'model_path': model_path,
|
||||
}
|
||||
return (easyanimate_model,)
|
||||
|
||||
|
||||
class TextBox:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"prompt": ("STRING", {"multiline": True, "default": "",}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING_PROMPT",)
|
||||
RETURN_NAMES =("prompt",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "EasyAnimateWrapper"
|
||||
|
||||
def process(self, prompt):
|
||||
return (prompt, )
|
||||
|
||||
|
||||
class EasyAnimateI2VSampler:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"easyanimate_model": (
|
||||
"EASYANIMATESMODEL",
|
||||
),
|
||||
"prompt": (
|
||||
"STRING_PROMPT",
|
||||
),
|
||||
"negative_prompt": (
|
||||
"STRING_PROMPT",
|
||||
),
|
||||
"video_length": (
|
||||
"INT", {"default": 72, "min": 8, "max": 144, "step": 8}
|
||||
),
|
||||
"base_resolution": (
|
||||
[
|
||||
512,
|
||||
768,
|
||||
960,
|
||||
], {"default": 768}
|
||||
),
|
||||
"seed": (
|
||||
"INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
|
||||
),
|
||||
"steps": (
|
||||
"INT", {"default": 25, "min": 1, "max": 200, "step": 1}
|
||||
),
|
||||
"cfg": (
|
||||
"FLOAT", {"default": 7.0, "min": 1.0, "max": 20.0, "step": 0.01}
|
||||
),
|
||||
"scheduler": (
|
||||
[
|
||||
"Euler",
|
||||
"Euler A",
|
||||
"DPM++",
|
||||
"PNDM",
|
||||
"DDIM",
|
||||
],
|
||||
{
|
||||
"default": 'Euler'
|
||||
}
|
||||
)
|
||||
},
|
||||
"optional":{
|
||||
"start_img": ("IMAGE",),
|
||||
"end_img": ("IMAGE",),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES =("images",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "EasyAnimateWrapper"
|
||||
|
||||
def process(self, easyanimate_model, prompt, negative_prompt, video_length, base_resolution, seed, steps, cfg, scheduler, start_img=None, end_img=None):
|
||||
device = mm.get_torch_device()
|
||||
offload_device = mm.unet_offload_device()
|
||||
|
||||
mm.soft_empty_cache()
|
||||
gc.collect()
|
||||
|
||||
start_img = [to_pil(_start_img) for _start_img in start_img] if start_img is not None else None
|
||||
end_img = [to_pil(_end_img) for _end_img in end_img] if end_img is not None else None
|
||||
# Count most suitable height and width
|
||||
aspect_ratio_sample_size = {key : [x / 512 * base_resolution for x in ASPECT_RATIO_512[key]] for key in ASPECT_RATIO_512.keys()}
|
||||
original_width, original_height = start_img[0].size if type(start_img) is list else Image.open(start_img).size
|
||||
closest_size, closest_ratio = get_closest_ratio(original_height, original_width, ratios=aspect_ratio_sample_size)
|
||||
height, width = [int(x / 16) * 16 for x in closest_size]
|
||||
|
||||
# Get Pipeline
|
||||
pipeline = easyanimate_model['pipeline']
|
||||
model_path = easyanimate_model['model_path']
|
||||
|
||||
# Load Sampler
|
||||
if scheduler == "DPM++":
|
||||
noise_scheduler = DPMSolverMultistepScheduler.from_pretrained(model_path, subfolder= 'scheduler')
|
||||
elif scheduler == "Euler":
|
||||
noise_scheduler = EulerDiscreteScheduler.from_pretrained(model_path, subfolder= 'scheduler')
|
||||
elif scheduler == "Euler A":
|
||||
noise_scheduler = EulerAncestralDiscreteScheduler.from_pretrained(model_path, subfolder= 'scheduler')
|
||||
elif scheduler == "PNDM":
|
||||
noise_scheduler = PNDMScheduler.from_pretrained(model_path, subfolder= 'scheduler')
|
||||
elif scheduler == "DDIM":
|
||||
noise_scheduler = DDIMScheduler.from_pretrained(model_path, subfolder= 'scheduler')
|
||||
pipeline.scheduler = noise_scheduler
|
||||
|
||||
generator= torch.Generator(device).manual_seed(seed)
|
||||
|
||||
with torch.no_grad():
|
||||
video_length = int(video_length // pipeline.vae.mini_batch_encoder * pipeline.vae.mini_batch_encoder) if video_length != 1 else 1
|
||||
input_video, input_video_mask, clip_image = get_image_to_video_latent(start_img, end_img, video_length=video_length, sample_size=(height, width))
|
||||
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
video_length = video_length,
|
||||
negative_prompt = negative_prompt,
|
||||
height = height,
|
||||
width = width,
|
||||
generator = generator,
|
||||
guidance_scale = cfg,
|
||||
num_inference_steps = steps,
|
||||
|
||||
video = input_video,
|
||||
mask_video = input_video_mask,
|
||||
clip_image = clip_image,
|
||||
comfyui_progressbar = True,
|
||||
).videos
|
||||
videos = rearrange(sample, "b c t h w -> (b t) h w c")
|
||||
return (videos,)
|
||||
|
||||
|
||||
class EasyAnimateT2VSampler:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"easyanimate_model": (
|
||||
"EASYANIMATESMODEL",
|
||||
),
|
||||
"prompt": (
|
||||
"STRING_PROMPT",
|
||||
),
|
||||
"negative_prompt": (
|
||||
"STRING_PROMPT",
|
||||
),
|
||||
"video_length": (
|
||||
"INT", {"default": 72, "min": 8, "max": 144, "step": 8}
|
||||
),
|
||||
"width": (
|
||||
"INT", {"default": 1008, "min": 64, "max": 2048, "step": 64}
|
||||
),
|
||||
"height": (
|
||||
"INT", {"default": 576, "min": 64, "max": 2048, "step": 64}
|
||||
),
|
||||
"is_image":(
|
||||
[
|
||||
False,
|
||||
True
|
||||
],
|
||||
{
|
||||
"default": False,
|
||||
}
|
||||
),
|
||||
"seed": (
|
||||
"INT", {"default": 43, "min": 0, "max": 0xffffffffffffffff}
|
||||
),
|
||||
"steps": (
|
||||
"INT", {"default": 25, "min": 1, "max": 200, "step": 1}
|
||||
),
|
||||
"cfg": (
|
||||
"FLOAT", {"default": 7.0, "min": 1.0, "max": 20.0, "step": 0.01}
|
||||
),
|
||||
"scheduler": (
|
||||
[
|
||||
"Euler",
|
||||
"Euler A",
|
||||
"DPM++",
|
||||
"PNDM",
|
||||
"DDIM",
|
||||
],
|
||||
{
|
||||
"default": 'Euler'
|
||||
}
|
||||
),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES =("images",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "EasyAnimateWrapper"
|
||||
|
||||
def process(self, easyanimate_model, prompt, negative_prompt, video_length, width, height, is_image, seed, steps, cfg, scheduler):
|
||||
device = mm.get_torch_device()
|
||||
offload_device = mm.unet_offload_device()
|
||||
|
||||
mm.soft_empty_cache()
|
||||
gc.collect()
|
||||
|
||||
# Get Pipeline
|
||||
pipeline = easyanimate_model['pipeline']
|
||||
model_path = easyanimate_model['model_path']
|
||||
|
||||
# Load Sampler
|
||||
if scheduler == "DPM++":
|
||||
noise_scheduler = DPMSolverMultistepScheduler.from_pretrained(model_path, subfolder= 'scheduler')
|
||||
elif scheduler == "Euler":
|
||||
noise_scheduler = EulerDiscreteScheduler.from_pretrained(model_path, subfolder= 'scheduler')
|
||||
elif scheduler == "Euler A":
|
||||
noise_scheduler = EulerAncestralDiscreteScheduler.from_pretrained(model_path, subfolder= 'scheduler')
|
||||
elif scheduler == "PNDM":
|
||||
noise_scheduler = PNDMScheduler.from_pretrained(model_path, subfolder= 'scheduler')
|
||||
elif scheduler == "DDIM":
|
||||
noise_scheduler = DDIMScheduler.from_pretrained(model_path, subfolder= 'scheduler')
|
||||
pipeline.scheduler = noise_scheduler
|
||||
|
||||
generator= torch.Generator(device).manual_seed(seed)
|
||||
|
||||
video_length = 1 if is_image else video_length
|
||||
with torch.no_grad():
|
||||
video_length = int(video_length // pipeline.vae.mini_batch_encoder * pipeline.vae.mini_batch_encoder) if video_length != 1 else 1
|
||||
input_video, input_video_mask, clip_image = get_image_to_video_latent(None, None, video_length=video_length, sample_size=(height, width))
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
video_length = video_length,
|
||||
negative_prompt = negative_prompt,
|
||||
height = height,
|
||||
width = width,
|
||||
generator = generator,
|
||||
guidance_scale = cfg,
|
||||
num_inference_steps = steps,
|
||||
|
||||
video = input_video,
|
||||
mask_video = input_video_mask,
|
||||
clip_image = clip_image,
|
||||
comfyui_progressbar = True,
|
||||
).videos
|
||||
videos = rearrange(sample, "b c t h w -> (b t) h w c")
|
||||
return (videos,)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"LoadEasyAnimateModel": LoadEasyAnimateModel,
|
||||
"TextBox": TextBox,
|
||||
"EasyAnimateI2VSampler": EasyAnimateI2VSampler,
|
||||
"EasyAnimateT2VSampler": EasyAnimateT2VSampler,
|
||||
}
|
||||
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"TextBox": "TextBox",
|
||||
"LoadEasyAnimateModel": "Load EasyAnimate Model",
|
||||
"EasyAnimateI2VSampler": "EasyAnimate Sampler for Image to Video",
|
||||
"EasyAnimateT2VSampler": "EasyAnimate Sampler for Text to Video",
|
||||
}
|
||||
@@ -0,0 +1,472 @@
|
||||
{
|
||||
"last_node_id": 81,
|
||||
"last_link_id": 41,
|
||||
"nodes": [
|
||||
{
|
||||
"id": 73,
|
||||
"type": "TextBox",
|
||||
"pos": [
|
||||
250,
|
||||
160
|
||||
],
|
||||
"size": {
|
||||
"0": 383.7149963378906,
|
||||
"1": 183.83506774902344
|
||||
},
|
||||
"flags": {},
|
||||
"order": 0,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "prompt",
|
||||
"type": "STRING_PROMPT",
|
||||
"links": [
|
||||
38
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"title": "Negtive Prompt(反向提示词)",
|
||||
"properties": {
|
||||
"Node name for S&R": "TextBox"
|
||||
},
|
||||
"widgets_values": [
|
||||
"The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion."
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 7,
|
||||
"type": "LoadImage",
|
||||
"pos": [
|
||||
258.76883544921907,
|
||||
468.15773315429715
|
||||
],
|
||||
"size": {
|
||||
"0": 378.07147216796875,
|
||||
"1": 314
|
||||
},
|
||||
"flags": {},
|
||||
"order": 1,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
39
|
||||
],
|
||||
"shape": 3,
|
||||
"label": "图像",
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "MASK",
|
||||
"type": "MASK",
|
||||
"links": null,
|
||||
"shape": 3,
|
||||
"label": "遮罩"
|
||||
}
|
||||
],
|
||||
"title": "Start Image(图片到视频的开始图片)",
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadImage"
|
||||
},
|
||||
"widgets_values": [
|
||||
"firework.png",
|
||||
"image"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 75,
|
||||
"type": "TextBox",
|
||||
"pos": [
|
||||
250,
|
||||
-50
|
||||
],
|
||||
"size": {
|
||||
"0": 383.54010009765625,
|
||||
"1": 156.71620178222656
|
||||
},
|
||||
"flags": {},
|
||||
"order": 2,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "prompt",
|
||||
"type": "STRING_PROMPT",
|
||||
"links": [
|
||||
37
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"title": "Positive Prompt(正向提示词)",
|
||||
"properties": {
|
||||
"Node name for S&R": "TextBox"
|
||||
},
|
||||
"widgets_values": [
|
||||
"fireworks display over night city. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 79,
|
||||
"type": "Note",
|
||||
"pos": [
|
||||
16,
|
||||
460
|
||||
],
|
||||
"size": {
|
||||
"0": 210,
|
||||
"1": 58
|
||||
},
|
||||
"flags": {},
|
||||
"order": 3,
|
||||
"mode": 0,
|
||||
"properties": {
|
||||
"text": ""
|
||||
},
|
||||
"widgets_values": [
|
||||
"You can upload image here\n(在此上传开始图像)"
|
||||
],
|
||||
"color": "#432",
|
||||
"bgcolor": "#653"
|
||||
},
|
||||
{
|
||||
"id": 80,
|
||||
"type": "Note",
|
||||
"pos": [
|
||||
20,
|
||||
-300
|
||||
],
|
||||
"size": [
|
||||
210,
|
||||
66.9820411046532
|
||||
],
|
||||
"flags": {},
|
||||
"order": 4,
|
||||
"mode": 0,
|
||||
"properties": {
|
||||
"text": ""
|
||||
},
|
||||
"widgets_values": [
|
||||
"Load model here\n(在此选择要使用的模型)"
|
||||
],
|
||||
"color": "#432",
|
||||
"bgcolor": "#653"
|
||||
},
|
||||
{
|
||||
"id": 78,
|
||||
"type": "Note",
|
||||
"pos": [
|
||||
18,
|
||||
-46
|
||||
],
|
||||
"size": {
|
||||
"0": 210,
|
||||
"1": 58
|
||||
},
|
||||
"flags": {},
|
||||
"order": 5,
|
||||
"mode": 0,
|
||||
"properties": {
|
||||
"text": ""
|
||||
},
|
||||
"widgets_values": [
|
||||
"You can write prompt here\n(你可以在此填写提示词)"
|
||||
],
|
||||
"color": "#432",
|
||||
"bgcolor": "#653"
|
||||
},
|
||||
{
|
||||
"id": 81,
|
||||
"type": "Note",
|
||||
"pos": [
|
||||
789,
|
||||
425
|
||||
],
|
||||
"size": [
|
||||
248.3692843737556,
|
||||
87.05973641715354
|
||||
],
|
||||
"flags": {},
|
||||
"order": 6,
|
||||
"mode": 0,
|
||||
"properties": {
|
||||
"text": ""
|
||||
},
|
||||
"widgets_values": [
|
||||
"Pay attention to selecting a base length that is compatible with the model\n(注意选择和模型相兼容的base length)"
|
||||
],
|
||||
"color": "#432",
|
||||
"bgcolor": "#653"
|
||||
},
|
||||
{
|
||||
"id": 31,
|
||||
"type": "LoadEasyAnimateModel",
|
||||
"pos": [
|
||||
240,
|
||||
-300
|
||||
],
|
||||
"size": {
|
||||
"0": 422.3550720214844,
|
||||
"1": 131.07559204101562
|
||||
},
|
||||
"flags": {},
|
||||
"order": 7,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "easyanimate_model",
|
||||
"type": "EASYANIMATESMODEL",
|
||||
"links": [
|
||||
35
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadEasyAnimateModel"
|
||||
},
|
||||
"widgets_values": [
|
||||
"EasyAnimateV3-XL-2-InP-768x768",
|
||||
false,
|
||||
"easyanimate_video_slicevae_motion_module_v3.yaml",
|
||||
"bf16"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 72,
|
||||
"type": "EasyAnimateI2VSampler",
|
||||
"pos": [
|
||||
761,
|
||||
93
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 282
|
||||
},
|
||||
"flags": {},
|
||||
"order": 8,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "easyanimate_model",
|
||||
"type": "EASYANIMATESMODEL",
|
||||
"link": 35
|
||||
},
|
||||
{
|
||||
"name": "prompt",
|
||||
"type": "STRING_PROMPT",
|
||||
"link": 37
|
||||
},
|
||||
{
|
||||
"name": "negative_prompt",
|
||||
"type": "STRING_PROMPT",
|
||||
"link": 38
|
||||
},
|
||||
{
|
||||
"name": "start_img",
|
||||
"type": "IMAGE",
|
||||
"link": 39
|
||||
},
|
||||
{
|
||||
"name": "end_img",
|
||||
"type": "IMAGE",
|
||||
"link": null
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
40
|
||||
],
|
||||
"shape": 3
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "EasyAnimateI2VSampler"
|
||||
},
|
||||
"widgets_values": [
|
||||
72,
|
||||
768,
|
||||
43,
|
||||
"fixed",
|
||||
25,
|
||||
7,
|
||||
"Euler"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 17,
|
||||
"type": "VHS_VideoCombine",
|
||||
"pos": [
|
||||
1134,
|
||||
93
|
||||
],
|
||||
"size": [
|
||||
390.9534912109375,
|
||||
535.9734235491071
|
||||
],
|
||||
"flags": {},
|
||||
"order": 9,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 40,
|
||||
"label": "图像",
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "audio",
|
||||
"type": "VHS_AUDIO",
|
||||
"link": null,
|
||||
"label": "音频"
|
||||
},
|
||||
{
|
||||
"name": "meta_batch",
|
||||
"type": "VHS_BatchManager",
|
||||
"link": null,
|
||||
"label": "批次管理"
|
||||
},
|
||||
{
|
||||
"name": "vae",
|
||||
"type": "VAE",
|
||||
"link": null
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "Filenames",
|
||||
"type": "VHS_FILENAMES",
|
||||
"links": null,
|
||||
"shape": 3,
|
||||
"label": "文件名",
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "VHS_VideoCombine"
|
||||
},
|
||||
"widgets_values": {
|
||||
"frame_rate": 24,
|
||||
"loop_count": 0,
|
||||
"filename_prefix": "EasyAnimate",
|
||||
"format": "video/h264-mp4",
|
||||
"pix_fmt": "yuv420p",
|
||||
"crf": 22,
|
||||
"save_metadata": true,
|
||||
"pingpong": false,
|
||||
"save_output": true,
|
||||
"videopreview": {
|
||||
"hidden": false,
|
||||
"paused": false,
|
||||
"params": {
|
||||
"filename": "EasyAnimate_00006.mp4",
|
||||
"subfolder": "",
|
||||
"type": "output",
|
||||
"format": "video/h264-mp4",
|
||||
"frame_rate": 24
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
],
|
||||
"links": [
|
||||
[
|
||||
35,
|
||||
31,
|
||||
0,
|
||||
72,
|
||||
0,
|
||||
"EASYANIMATESMODEL"
|
||||
],
|
||||
[
|
||||
37,
|
||||
75,
|
||||
0,
|
||||
72,
|
||||
1,
|
||||
"STRING_PROMPT"
|
||||
],
|
||||
[
|
||||
38,
|
||||
73,
|
||||
0,
|
||||
72,
|
||||
2,
|
||||
"STRING_PROMPT"
|
||||
],
|
||||
[
|
||||
39,
|
||||
7,
|
||||
0,
|
||||
72,
|
||||
3,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
40,
|
||||
72,
|
||||
0,
|
||||
17,
|
||||
0,
|
||||
"IMAGE"
|
||||
]
|
||||
],
|
||||
"groups": [
|
||||
{
|
||||
"title": "Prompts",
|
||||
"bounding": [
|
||||
218,
|
||||
-127,
|
||||
450,
|
||||
483
|
||||
],
|
||||
"color": "#3f789e",
|
||||
"font_size": 24
|
||||
},
|
||||
{
|
||||
"title": "Load EasyAnimate",
|
||||
"bounding": [
|
||||
220,
|
||||
-380,
|
||||
472,
|
||||
232
|
||||
],
|
||||
"color": "#b06634",
|
||||
"font_size": 24
|
||||
},
|
||||
{
|
||||
"title": "Upload Your Start Image",
|
||||
"bounding": [
|
||||
218,
|
||||
382,
|
||||
452,
|
||||
418
|
||||
],
|
||||
"color": "#a1309b",
|
||||
"font_size": 24
|
||||
}
|
||||
],
|
||||
"config": {},
|
||||
"extra": {
|
||||
"ds": {
|
||||
"scale": 0.7513148009015778,
|
||||
"offset": [
|
||||
271.2395710949943,
|
||||
427.25806436409613
|
||||
]
|
||||
},
|
||||
"workspace_info": {
|
||||
"id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
|
||||
}
|
||||
},
|
||||
"version": 0.4
|
||||
}
|
||||
@@ -0,0 +1,382 @@
|
||||
{
|
||||
"last_node_id": 85,
|
||||
"last_link_id": 48,
|
||||
"nodes": [
|
||||
{
|
||||
"id": 80,
|
||||
"type": "Note",
|
||||
"pos": [
|
||||
20,
|
||||
-300
|
||||
],
|
||||
"size": {
|
||||
"0": 210,
|
||||
"1": 66.98204040527344
|
||||
},
|
||||
"flags": {},
|
||||
"order": 0,
|
||||
"mode": 0,
|
||||
"properties": {
|
||||
"text": ""
|
||||
},
|
||||
"widgets_values": [
|
||||
"Load model here\n(在此选择要使用的模型)"
|
||||
],
|
||||
"color": "#432",
|
||||
"bgcolor": "#653"
|
||||
},
|
||||
{
|
||||
"id": 78,
|
||||
"type": "Note",
|
||||
"pos": [
|
||||
18,
|
||||
-46
|
||||
],
|
||||
"size": {
|
||||
"0": 210,
|
||||
"1": 58
|
||||
},
|
||||
"flags": {},
|
||||
"order": 1,
|
||||
"mode": 0,
|
||||
"properties": {
|
||||
"text": ""
|
||||
},
|
||||
"widgets_values": [
|
||||
"You can write prompt here\n(你可以在此填写提示词)"
|
||||
],
|
||||
"color": "#432",
|
||||
"bgcolor": "#653"
|
||||
},
|
||||
{
|
||||
"id": 31,
|
||||
"type": "LoadEasyAnimateModel",
|
||||
"pos": [
|
||||
240,
|
||||
-300
|
||||
],
|
||||
"size": {
|
||||
"0": 422.3550720214844,
|
||||
"1": 131.07559204101562
|
||||
},
|
||||
"flags": {},
|
||||
"order": 2,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "easyanimate_model",
|
||||
"type": "EASYANIMATESMODEL",
|
||||
"links": [
|
||||
47
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadEasyAnimateModel"
|
||||
},
|
||||
"widgets_values": [
|
||||
"EasyAnimateV3-XL-2-InP-768x768",
|
||||
false,
|
||||
"easyanimate_video_slicevae_motion_module_v3.yaml",
|
||||
"bf16"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 73,
|
||||
"type": "TextBox",
|
||||
"pos": [
|
||||
250,
|
||||
160
|
||||
],
|
||||
"size": {
|
||||
"0": 383.7149963378906,
|
||||
"1": 183.83506774902344
|
||||
},
|
||||
"flags": {},
|
||||
"order": 3,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "prompt",
|
||||
"type": "STRING_PROMPT",
|
||||
"links": [
|
||||
46
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"title": "Negtive Prompt(反向提示词)",
|
||||
"properties": {
|
||||
"Node name for S&R": "TextBox"
|
||||
},
|
||||
"widgets_values": [
|
||||
"The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion."
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 17,
|
||||
"type": "VHS_VideoCombine",
|
||||
"pos": [
|
||||
1148,
|
||||
15
|
||||
],
|
||||
"size": [
|
||||
390.9534912109375,
|
||||
535.9734235491071
|
||||
],
|
||||
"flags": {},
|
||||
"order": 7,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 48,
|
||||
"label": "图像",
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "audio",
|
||||
"type": "VHS_AUDIO",
|
||||
"link": null,
|
||||
"label": "音频"
|
||||
},
|
||||
{
|
||||
"name": "meta_batch",
|
||||
"type": "VHS_BatchManager",
|
||||
"link": null,
|
||||
"label": "批次管理"
|
||||
},
|
||||
{
|
||||
"name": "vae",
|
||||
"type": "VAE",
|
||||
"link": null
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "Filenames",
|
||||
"type": "VHS_FILENAMES",
|
||||
"links": null,
|
||||
"shape": 3,
|
||||
"label": "文件名",
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "VHS_VideoCombine"
|
||||
},
|
||||
"widgets_values": {
|
||||
"frame_rate": 24,
|
||||
"loop_count": 0,
|
||||
"filename_prefix": "EasyAnimate",
|
||||
"format": "video/h264-mp4",
|
||||
"pix_fmt": "yuv420p",
|
||||
"crf": 22,
|
||||
"save_metadata": true,
|
||||
"pingpong": false,
|
||||
"save_output": true,
|
||||
"videopreview": {
|
||||
"hidden": false,
|
||||
"paused": false,
|
||||
"params": {
|
||||
"filename": "EasyAnimate_00007.mp4",
|
||||
"subfolder": "",
|
||||
"type": "output",
|
||||
"format": "video/h264-mp4",
|
||||
"frame_rate": 24
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
{
|
||||
"id": 75,
|
||||
"type": "TextBox",
|
||||
"pos": [
|
||||
250,
|
||||
-50
|
||||
],
|
||||
"size": {
|
||||
"0": 383.54010009765625,
|
||||
"1": 156.71620178222656
|
||||
},
|
||||
"flags": {},
|
||||
"order": 4,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "prompt",
|
||||
"type": "STRING_PROMPT",
|
||||
"links": [
|
||||
45
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"title": "Positive Prompt(正向提示词)",
|
||||
"properties": {
|
||||
"Node name for S&R": "TextBox"
|
||||
},
|
||||
"widgets_values": [
|
||||
"A young woman with beautiful and clear eyes and blonde hair standing and white dress in a forest wearing a crown. She seems to be lost in thought, and the camera focuses on her face. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 85,
|
||||
"type": "EasyAnimateT2VSampler",
|
||||
"pos": [
|
||||
769,
|
||||
15
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 290
|
||||
},
|
||||
"flags": {},
|
||||
"order": 6,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "easyanimate_model",
|
||||
"type": "EASYANIMATESMODEL",
|
||||
"link": 47,
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "prompt",
|
||||
"type": "STRING_PROMPT",
|
||||
"link": 45
|
||||
},
|
||||
{
|
||||
"name": "negative_prompt",
|
||||
"type": "STRING_PROMPT",
|
||||
"link": 46
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
48
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "EasyAnimateT2VSampler"
|
||||
},
|
||||
"widgets_values": [
|
||||
72,
|
||||
1008,
|
||||
576,
|
||||
false,
|
||||
43,
|
||||
"fixed",
|
||||
25,
|
||||
7,
|
||||
"Euler"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 81,
|
||||
"type": "Note",
|
||||
"pos": [
|
||||
750,
|
||||
-261
|
||||
],
|
||||
"size": [
|
||||
376.27749140500555,
|
||||
224.3558848546536
|
||||
],
|
||||
"flags": {},
|
||||
"order": 5,
|
||||
"mode": 0,
|
||||
"properties": {
|
||||
"text": ""
|
||||
},
|
||||
"widgets_values": [
|
||||
"Pay attention to selecting a width and height compatible with the model;\nThe commonly used resolution for the 512x512 model is width=672 height=384;\nThe commonly used resolution for the 768x768 model is width=1008 height=576;\nThe commonly used resolution for the 1024x1024 model is width=1244 height=720;\n\n(注意选择和模型相兼容的高和宽;\n512x512模型的常用分辨率是width=672 height=384;\n768x768模型的常用分辨率是width=1008 height=576;\n1024x1024模型的常用分辨率是width=1244 height=720;)"
|
||||
],
|
||||
"color": "#432",
|
||||
"bgcolor": "#653"
|
||||
}
|
||||
],
|
||||
"links": [
|
||||
[
|
||||
45,
|
||||
75,
|
||||
0,
|
||||
85,
|
||||
1,
|
||||
"STRING_PROMPT"
|
||||
],
|
||||
[
|
||||
46,
|
||||
73,
|
||||
0,
|
||||
85,
|
||||
2,
|
||||
"STRING_PROMPT"
|
||||
],
|
||||
[
|
||||
47,
|
||||
31,
|
||||
0,
|
||||
85,
|
||||
0,
|
||||
"EASYANIMATESMODEL"
|
||||
],
|
||||
[
|
||||
48,
|
||||
85,
|
||||
0,
|
||||
17,
|
||||
0,
|
||||
"IMAGE"
|
||||
]
|
||||
],
|
||||
"groups": [
|
||||
{
|
||||
"title": "Prompts",
|
||||
"bounding": [
|
||||
218,
|
||||
-127,
|
||||
450,
|
||||
483
|
||||
],
|
||||
"color": "#3f789e",
|
||||
"font_size": 24
|
||||
},
|
||||
{
|
||||
"title": "Load EasyAnimate",
|
||||
"bounding": [
|
||||
220,
|
||||
-380,
|
||||
472,
|
||||
232
|
||||
],
|
||||
"color": "#b06634",
|
||||
"font_size": 24
|
||||
}
|
||||
],
|
||||
"config": {},
|
||||
"extra": {
|
||||
"ds": {
|
||||
"scale": 0.9090909090909092,
|
||||
"offset": [
|
||||
33.575633594994244,
|
||||
458.8503651453463
|
||||
]
|
||||
},
|
||||
"workspace_info": {
|
||||
"id": "776b62b4-bd17-4ed3-9923-b7aad000b1ea"
|
||||
}
|
||||
},
|
||||
"version": 0.4
|
||||
}
|
||||
Reference in New Issue
Block a user