Update readme and report, fix bug in training code, gallery and 5b model (#2)
This commit is contained in:
 Bubbliiiing
@@ -8,6 +8,7 @@ English | [简体中文](./README_zh-CN.md)
|
||||
- [Table of Contents](#table-of-contents)
|
||||
- [Introduction](#introduction)
|
||||
- [Quick Start](#quick-start)
|
||||
- [Video Result](#video-result)
|
||||
- [How to use](#how-to-use)
|
||||
- [Model zoo](#model-zoo)
|
||||
- [TODO List](#todo-list)
|
||||
@@ -20,22 +21,24 @@ CogVideoX-Fun is a modified pipeline based on the CogVideoX structure, designed
|
||||
We will support quick pull-ups from different platforms, refer to [Quick Start](#quick-start).
|
||||
|
||||
What's New:
|
||||
- Create code! Now supporting Windows and Linux. Supports video generation at any resolution from 256x256x49 to 1024x1024x49. [ 2024.09.09 ]
|
||||
- Create code! Now supporting Windows and Linux. Supports 2b and 5b models. Supports video generation at any resolution from 256x256x49 to 1024x1024x49. [ 2024.09.09 ]
|
||||
|
||||
Function:
|
||||
- [Data Preprocessing](#data-preprocess)
|
||||
- [Train DiT](#dit-train)
|
||||
- [Video Generation](#video-gen)
|
||||
|
||||
These are our generated results [GALLERY](scripts/Result_Gallery.md) (Click the image below to see the video):
|
||||
|
||||
Our UI interface is as follows:
|
||||
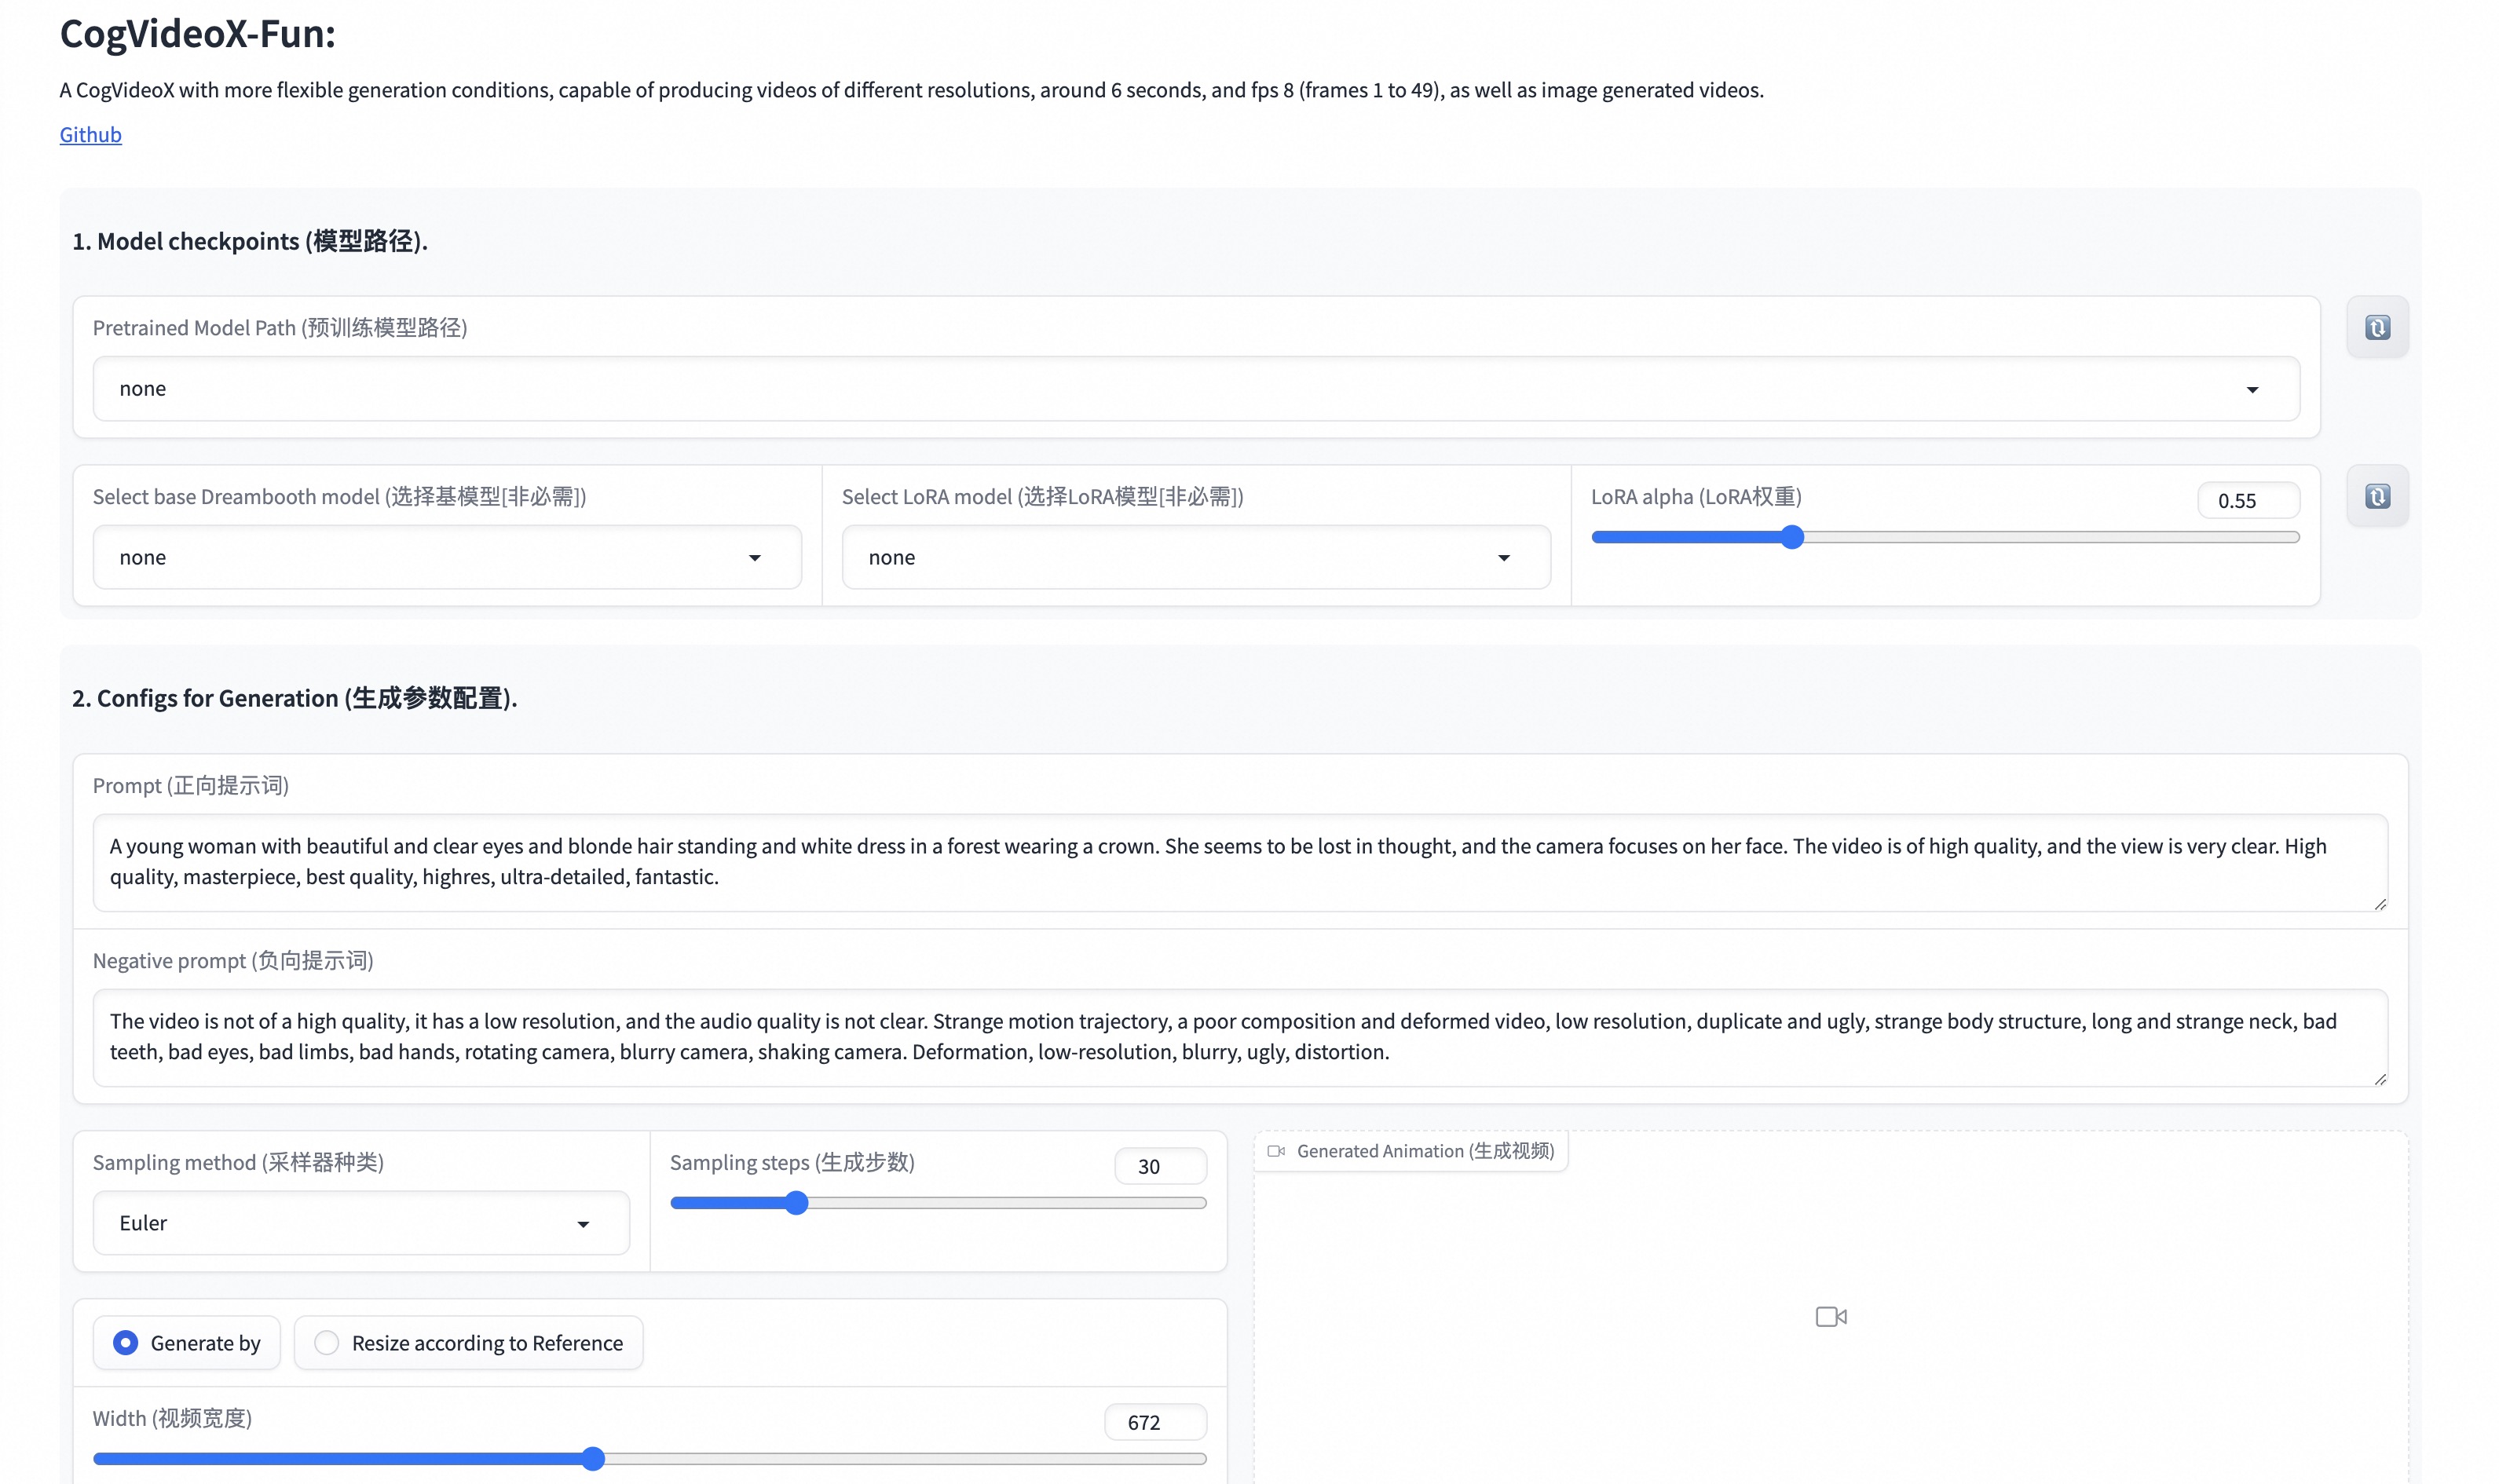
|
||||
|
||||
# Quick Start
|
||||
### 1. Cloud usage: AliyunDSW/Docker
|
||||
#### a. From AliyunDSW
|
||||
On the way.
|
||||
DSW has free GPU time, which can be applied once by a user and is valid for 3 months after applying.
|
||||
|
||||
Aliyun provide free GPU time in [Freetier](https://free.aliyun.com/?product=9602825&crowd=enterprise&spm=5176.28055625.J_5831864660.1.e939154aRgha4e&scm=20140722.M_9974135.P_110.MO_1806-ID_9974135-MID_9974135-CID_30683-ST_8512-V_1), get it and use in Aliyun PAI-DSW to start CogVideoX-Fun within 5min!
|
||||
|
||||
[](https://gallery.pai-ml.com/#/preview/deepLearning/cv/cogvideox_fun)
|
||||
|
||||
#### b. From ComfyUI
|
||||
Our ComfyUI is as follows, please refer to [ComfyUI README](comfyui/README.md) for details.
|
||||
@@ -64,9 +67,11 @@ mkdir models/Diffusion_Transformer
|
||||
mkdir models/Personalized_Model
|
||||
|
||||
wget https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz -O models/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz
|
||||
wget https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz -O models/Diffusion_Transformer/CogVideoX-Fun-5b-InP.tar.gz
|
||||
|
||||
cd models/Diffusion_Transformer/
|
||||
tar -xvf CogVideoX-Fun-2b-InP.tar.gz
|
||||
tar -xvf CogVideoX-Fun-5b-InP.tar.gz
|
||||
cd ../../
|
||||
```
|
||||
|
||||
@@ -98,11 +103,93 @@ We'd better place the [weights](#model-zoo) along the specified path:
|
||||
```
|
||||
📦 models/
|
||||
├── 📂 Diffusion_Transformer/
|
||||
│ └── 📂 CogVideoX-Fun-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-2b-InP/
|
||||
│ └── 📂 CogVideoX-Fun-5b-InP/
|
||||
├── 📂 Personalized_Model/
|
||||
│ └── your trained trainformer model / your trained lora model (for UI load)
|
||||
```
|
||||
|
||||
# Video Result
|
||||
The results displayed are all based on image.
|
||||
|
||||
### CogVideoX-5B
|
||||
|
||||
Resolution-1024
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_1024/00000001.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_1024/00000002.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_1024/00000003.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_1024/00000004.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
Resolution-768
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_768/00000001.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_768/00000002.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_768/00000003.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_768/00000004.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
Resolution-512
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_512/00000001.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_512/00000002.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_512/00000003.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_512/00000004.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-2B
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/2b_768/00000001.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/2b_768/00000002.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/2b_768/00000003.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/2b_768/00000004.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
# How to use
|
||||
|
||||
<h3 id="video-gen">1. Inference </h3>
|
||||
@@ -204,9 +291,10 @@ For details on setting some parameters, please refer to [Readme Train](scripts/R
|
||||
| Name | Storage Space | Url | Hugging Face | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP.tar.gz | Before extraction:9.69 GB \/ After extraction: 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 144 frames at a rate of 24 frames per second. |
|
||||
| CogVideoX-Fun-5b-InP.tar.gz | Before extraction:9.69 GB \/ After extraction: 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-5b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 144 frames at a rate of 24 frames per second. |
|
||||
|
||||
# TODO List
|
||||
- Support CogVideoX-5b.
|
||||
- Support Chinese.
|
||||
|
||||
# Reference
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
@@ -215,4 +303,6 @@ For details on setting some parameters, please refer to [Readme Train](scripts/R
|
||||
# License
|
||||
This project is licensed under the [Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE).
|
||||
|
||||
The CogVideoX-2B model (including its corresponding Transformers module and VAE module) is released under the [Apache 2.0 License](LICENSE).
|
||||
The CogVideoX-2B model (including its corresponding Transformers module and VAE module) is released under the [Apache 2.0 License](LICENSE).
|
||||
|
||||
The CogVideoX-5B model (Transformers module) is released under the [CogVideoX LICENSE](https://huggingface.co/THUDM/CogVideoX-5b/blob/main/LICENSE).
|
||||
+98
-7
@@ -8,6 +8,7 @@
|
||||
- [目录](#目录)
|
||||
- [简介](#简介)
|
||||
- [快速启动](#快速启动)
|
||||
- [视频作品](#视频作品)
|
||||
- [如何使用](#如何使用)
|
||||
- [模型地址](#模型地址)
|
||||
- [未来计划](#未来计划)
|
||||
@@ -20,22 +21,24 @@ CogVideoX-Fun是一个基于CogVideoX结构修改后的的pipeline,是一个
|
||||
我们会逐渐支持从不同平台快速启动,请参阅 [快速启动](#快速启动)。
|
||||
|
||||
新特性:
|
||||
- 创建代码!现在支持 Windows 和 Linux。支持最大256x256x49到1024x1024x49的任意分辨率的视频生成。[ 2024.09.09 ]
|
||||
- 创建代码!现在支持 Windows 和 Linux。支持2b与5b最大256x256x49到1024x1024x49的任意分辨率的视频生成。[ 2024.09.09 ]
|
||||
|
||||
功能概览:
|
||||
- [数据预处理](#data-preprocess)
|
||||
- [训练DiT](#dit-train)
|
||||
- [模型生成](#video-gen)
|
||||
|
||||
这些是我们的生成结果 [GALLERY](scripts/Result_Gallery.md) (点击下方的图片可查看视频):
|
||||
|
||||
我们的ui界面如下:
|
||||

|
||||
|
||||
# 快速启动
|
||||
### 1. 云使用: AliyunDSW/Docker
|
||||
#### a. 通过阿里云 DSW
|
||||
正在路上
|
||||
DSW 有免费 GPU 时间,用户可申请一次,申请后3个月内有效。
|
||||
|
||||
阿里云在[Freetier](https://free.aliyun.com/?product=9602825&crowd=enterprise&spm=5176.28055625.J_5831864660.1.e939154aRgha4e&scm=20140722.M_9974135.P_110.MO_1806-ID_9974135-MID_9974135-CID_30683-ST_8512-V_1)提供免费GPU时间,获取并在阿里云PAI-DSW中使用,5分钟内即可启动CogVideoX-Fun。
|
||||
|
||||
[](https://gallery.pai-ml.com/#/preview/deepLearning/cv/cogvideox_fun)
|
||||
|
||||
#### b. 通过ComfyUI
|
||||
我们的ComfyUI界面如下,具体查看[ComfyUI README](comfyui/README.md)。
|
||||
@@ -62,9 +65,11 @@ mkdir models/Diffusion_Transformer
|
||||
mkdir models/Personalized_Model
|
||||
|
||||
wget https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz -O models/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz
|
||||
wget https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz -O models/Diffusion_Transformer/CogVideoX-Fun-5b-InP.tar.gz
|
||||
|
||||
cd models/Diffusion_Transformer/
|
||||
tar -xvf CogVideoX-Fun-2b-InP.tar.gz
|
||||
tar -xvf CogVideoX-Fun-5b-InP.tar.gz
|
||||
cd ../../
|
||||
```
|
||||
|
||||
@@ -96,11 +101,94 @@ Linux 的详细信息:
|
||||
```
|
||||
📦 models/
|
||||
├── 📂 Diffusion_Transformer/
|
||||
│ └── 📂 CogVideoX-Fun-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-2b-InP/
|
||||
│ └── 📂 CogVideoX-Fun-5b-InP/
|
||||
├── 📂 Personalized_Model/
|
||||
│ └── your trained trainformer model / your trained lora model (for UI load)
|
||||
```
|
||||
|
||||
# 视频作品
|
||||
所展示的结果都是图生视频获得。
|
||||
|
||||
### CogVideoX-5B
|
||||
|
||||
1024分辨率
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_1024/00000001.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_1024/00000002.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_1024/00000003.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_1024/00000004.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
768分辨率
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_768/00000001.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_768/00000002.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_768/00000003.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_768/00000004.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
512分辨率
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_512/00000001.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_512/00000002.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_512/00000003.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/5b_512/00000004.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-2B
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/2b_768/00000001.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/2b_768/00000002.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/2b_768/00000003.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/2b_768/00000004.mp4" width="100%" controls autoplay loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
# 如何使用
|
||||
|
||||
<h3 id="video-gen">1. 生成 </h3>
|
||||
@@ -202,9 +290,10 @@ sh scripts/train.sh
|
||||
| 名称 | 存储空间 | 下载地址 | Hugging Face | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP.tar.gz | 解压前 9.69 GB / 解压后 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP)| 官方的图生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以144帧、每秒24帧进行训练 |
|
||||
| CogVideoX-Fun-5b-InP.tar.gz | 解压前 9.69 GB / 解压后 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-5b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP)| 官方的图生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以144帧、每秒24帧进行训练 |
|
||||
|
||||
# 未来计划
|
||||
- 支持CogVideoX-5b。
|
||||
- 支持中文。
|
||||
|
||||
# 参考文献
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
@@ -213,4 +302,6 @@ sh scripts/train.sh
|
||||
# 许可证
|
||||
本项目采用 [Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE).
|
||||
|
||||
CogVideoX-2B 模型 (包括其对应的Transformers模块,VAE模块) 根据 [Apache 2.0 协议](LICENSE) 许可证发布。
|
||||
CogVideoX-2B 模型 (包括其对应的Transformers模块,VAE模块) 根据 [Apache 2.0 协议](LICENSE) 许可证发布。
|
||||
|
||||
CogVideoX-5B 模型(Transformer 模块)在[CogVideoX许可证](https://huggingface.co/THUDM/CogVideoX-5b/blob/main/LICENSE)下发布.
|
||||
@@ -18,6 +18,7 @@ from typing import Any, Dict, Optional, Tuple, Union
|
||||
import os
|
||||
import json
|
||||
import torch
|
||||
import glob
|
||||
import torch.nn.functional as F
|
||||
from torch import nn
|
||||
|
||||
@@ -517,13 +518,19 @@ class CogVideoXTransformer3DModel(ModelMixin, ConfigMixin):
|
||||
model = cls.from_config(config, **transformer_additional_kwargs)
|
||||
model_file = os.path.join(pretrained_model_path, WEIGHTS_NAME)
|
||||
model_file_safetensors = model_file.replace(".bin", ".safetensors")
|
||||
if os.path.exists(model_file_safetensors):
|
||||
if os.path.exists(model_file):
|
||||
state_dict = torch.load(model_file, map_location="cpu")
|
||||
elif os.path.exists(model_file_safetensors):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(model_file_safetensors)
|
||||
else:
|
||||
if not os.path.isfile(model_file):
|
||||
raise RuntimeError(f"{model_file} does not exist")
|
||||
state_dict = torch.load(model_file, map_location="cpu")
|
||||
from safetensors.torch import load_file, safe_open
|
||||
model_files_safetensors = glob.glob(os.path.join(pretrained_model_path, "*.safetensors"))
|
||||
state_dict = {}
|
||||
for model_file_safetensors in model_files_safetensors:
|
||||
_state_dict = load_file(model_file_safetensors)
|
||||
for key in _state_dict:
|
||||
state_dict[key] = _state_dict[key]
|
||||
|
||||
if model.state_dict()['patch_embed.proj.weight'].size() != state_dict['patch_embed.proj.weight'].size():
|
||||
new_shape = model.state_dict()['patch_embed.proj.weight'].size()
|
||||
|
||||
@@ -105,7 +105,7 @@ def get_image_to_video_latent(validation_image_start, validation_image_end, vide
|
||||
[1, 1, video_length, 1, 1]
|
||||
)
|
||||
input_video_mask = torch.zeros_like(input_video[:, :1])
|
||||
input_video_mask[:, :, 3:] = 255
|
||||
input_video_mask[:, :, 1:] = 255
|
||||
|
||||
if type(image_end) is list:
|
||||
image_end = [_image_end.resize(image_start[0].size if type(image_start) is list else image_start.size) for _image_end in image_end]
|
||||
@@ -118,8 +118,8 @@ def get_image_to_video_latent(validation_image_start, validation_image_end, vide
|
||||
input_video_mask[:, :, -len(image_end):] = 0
|
||||
else:
|
||||
image_end = image_end.resize(image_start[0].size if type(image_start) is list else image_start.size)
|
||||
input_video[:, :, -3:] = torch.from_numpy(np.array(image_end)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0)
|
||||
input_video_mask[:, :, -3:] = 0
|
||||
input_video[:, :, -1:] = torch.from_numpy(np.array(image_end)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0)
|
||||
input_video_mask[:, :, -1:] = 0
|
||||
|
||||
input_video = input_video / 255
|
||||
|
||||
@@ -152,7 +152,7 @@ def get_image_to_video_latent(validation_image_start, validation_image_end, vide
|
||||
[1, 1, video_length, 1, 1]
|
||||
) / 255
|
||||
input_video_mask = torch.zeros_like(input_video[:, :1])
|
||||
input_video_mask[:, :, 3:, ] = 255
|
||||
input_video_mask[:, :, 1:, ] = 255
|
||||
else:
|
||||
image_start = None
|
||||
image_end = None
|
||||
|
||||
@@ -31,6 +31,7 @@ python install.py
|
||||
| Name | Storage Space | Url | Hugging Face | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP.tar.gz | Before extraction:9.69 GB \/ After extraction: 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 144 frames at a rate of 24 frames per second. |
|
||||
| CogVideoX-Fun-5b-InP.tar.gz | Before extraction:9.69 GB \/ After extraction: 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-5b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 144 frames at a rate of 24 frames per second. |
|
||||
|
||||
## Node types
|
||||
- **LoadCogVideoX_Fun_Model**
|
||||
|
||||
@@ -58,6 +58,7 @@ class LoadCogVideoX_Fun_Model:
|
||||
"model": (
|
||||
[
|
||||
'CogVideoX-Fun-2b-InP',
|
||||
'CogVideoX-Fun-5b-InP',
|
||||
],
|
||||
{
|
||||
"default": 'CogVideoX-Fun-2b-InP',
|
||||
|
||||
@@ -113,40 +113,6 @@
|
||||
"color": "#432",
|
||||
"bgcolor": "#653"
|
||||
},
|
||||
{
|
||||
"id": 83,
|
||||
"type": "LoadCogVideoX_Fun_Model",
|
||||
"pos": [
|
||||
300,
|
||||
-294
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 106
|
||||
},
|
||||
"flags": {},
|
||||
"order": 4,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "cogvideoxfun_model",
|
||||
"type": "CogVideoXFUNSMODEL",
|
||||
"links": [
|
||||
42
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadCogVideoX_Fun_Model"
|
||||
},
|
||||
"widgets_values": [
|
||||
"CogVideoX-Fun-2b-InP",
|
||||
false,
|
||||
"fp16"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 75,
|
||||
"type": "TextBox",
|
||||
@@ -159,7 +125,7 @@
|
||||
"1": 156.71620178222656
|
||||
},
|
||||
"flags": {},
|
||||
"order": 5,
|
||||
"order": 4,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
@@ -192,7 +158,7 @@
|
||||
"1": 183.83506774902344
|
||||
},
|
||||
"flags": {},
|
||||
"order": 6,
|
||||
"order": 5,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
@@ -221,7 +187,7 @@
|
||||
93
|
||||
],
|
||||
"size": {
|
||||
"0": 317.4000244140625,
|
||||
"0": 336,
|
||||
"1": 282
|
||||
},
|
||||
"flags": {},
|
||||
@@ -346,14 +312,48 @@
|
||||
"hidden": false,
|
||||
"paused": false,
|
||||
"params": {
|
||||
"filename": "EasyAnimate_00040.mp4",
|
||||
"filename": "CogVideoX-Fun_00003.mp4",
|
||||
"subfolder": "",
|
||||
"type": "output",
|
||||
"format": "video/h264-mp4",
|
||||
"frame_rate": 24
|
||||
"frame_rate": 8
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
{
|
||||
"id": 83,
|
||||
"type": "LoadCogVideoX_Fun_Model",
|
||||
"pos": [
|
||||
300,
|
||||
-294
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 106
|
||||
},
|
||||
"flags": {},
|
||||
"order": 6,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "cogvideoxfun_model",
|
||||
"type": "CogVideoXFUNSMODEL",
|
||||
"links": [
|
||||
42
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadCogVideoX_Fun_Model"
|
||||
},
|
||||
"widgets_values": [
|
||||
"CogVideoX-Fun-2b-InP",
|
||||
false,
|
||||
"bf16"
|
||||
]
|
||||
}
|
||||
],
|
||||
"links": [
|
||||
|
||||
@@ -81,40 +81,6 @@
|
||||
"The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion."
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 87,
|
||||
"type": "LoadCogVideoX_Fun_Model",
|
||||
"pos": [
|
||||
302,
|
||||
-285
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 106
|
||||
},
|
||||
"flags": {},
|
||||
"order": 3,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "cogvideoxfun_model",
|
||||
"type": "CogVideoXFUNSMODEL",
|
||||
"links": [
|
||||
49
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadCogVideoX_Fun_Model"
|
||||
},
|
||||
"widgets_values": [
|
||||
"CogVideoX-Fun-2b-InP",
|
||||
false,
|
||||
"fp16"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 75,
|
||||
"type": "TextBox",
|
||||
@@ -127,7 +93,7 @@
|
||||
"1": 156.71620178222656
|
||||
},
|
||||
"flags": {},
|
||||
"order": 4,
|
||||
"order": 3,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
@@ -273,14 +239,48 @@
|
||||
"hidden": false,
|
||||
"paused": false,
|
||||
"params": {
|
||||
"filename": "EasyAnimate_00039.mp4",
|
||||
"filename": "CogVideoX-Fun_00004.mp4",
|
||||
"subfolder": "",
|
||||
"type": "output",
|
||||
"format": "video/h264-mp4",
|
||||
"frame_rate": 24
|
||||
"frame_rate": 8
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
{
|
||||
"id": 87,
|
||||
"type": "LoadCogVideoX_Fun_Model",
|
||||
"pos": [
|
||||
302,
|
||||
-285
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 106
|
||||
},
|
||||
"flags": {},
|
||||
"order": 4,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "cogvideoxfun_model",
|
||||
"type": "CogVideoXFUNSMODEL",
|
||||
"links": [
|
||||
49
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadCogVideoX_Fun_Model"
|
||||
},
|
||||
"widgets_values": [
|
||||
"CogVideoX-Fun-2b-InP",
|
||||
false,
|
||||
"bf16"
|
||||
]
|
||||
}
|
||||
],
|
||||
"links": [
|
||||
|
||||
@@ -187,40 +187,6 @@
|
||||
"The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion."
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 88,
|
||||
"type": "LoadCogVideoX_Fun_Model",
|
||||
"pos": [
|
||||
309,
|
||||
-286
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 106
|
||||
},
|
||||
"flags": {},
|
||||
"order": 5,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "cogvideoxfun_model",
|
||||
"type": "CogVideoXFUNSMODEL",
|
||||
"links": [
|
||||
52
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadCogVideoX_Fun_Model"
|
||||
},
|
||||
"widgets_values": [
|
||||
"CogVideoX-Fun-2b-InP",
|
||||
false,
|
||||
"fp16"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 75,
|
||||
"type": "TextBox",
|
||||
@@ -233,7 +199,7 @@
|
||||
"1": 156.71620178222656
|
||||
},
|
||||
"flags": {},
|
||||
"order": 6,
|
||||
"order": 5,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
@@ -262,7 +228,7 @@
|
||||
93
|
||||
],
|
||||
"size": {
|
||||
"0": 317.4000244140625,
|
||||
"0": 336,
|
||||
"1": 286
|
||||
},
|
||||
"flags": {},
|
||||
@@ -384,7 +350,7 @@
|
||||
"hidden": false,
|
||||
"paused": false,
|
||||
"params": {
|
||||
"filename": "EasyAnimate_00042.mp4",
|
||||
"filename": "EasyAnimate_00045.mp4",
|
||||
"subfolder": "",
|
||||
"type": "output",
|
||||
"format": "video/h264-mp4",
|
||||
@@ -392,6 +358,40 @@
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
{
|
||||
"id": 88,
|
||||
"type": "LoadCogVideoX_Fun_Model",
|
||||
"pos": [
|
||||
309,
|
||||
-286
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 106
|
||||
},
|
||||
"flags": {},
|
||||
"order": 6,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "cogvideoxfun_model",
|
||||
"type": "CogVideoXFUNSMODEL",
|
||||
"links": [
|
||||
52
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadCogVideoX_Fun_Model"
|
||||
},
|
||||
"widgets_values": [
|
||||
"CogVideoX-Fun-2b-InP",
|
||||
false,
|
||||
"bf16"
|
||||
]
|
||||
}
|
||||
],
|
||||
"links": [
|
||||
|
||||
@@ -0,0 +1,36 @@
|
||||
# CogVideoX FUN v1 Report
|
||||
In CogVideoX-FUN, we trained on approximately 1.2 million data points based on CogVideoX, supporting image and video predictions. It accommodates pixel values for video generation across different resolutions of 512x512x49, 768x768x49, and 1024x1024x49, as well as videos with different aspect ratios. Moreover, we support the generation of videos from images and the reconstruction of videos from other videos.
|
||||
|
||||
Compared to CogVideoX, CogVideoX FUN also highlights the following features:
|
||||
- Introduction of the InPaint model, enabling the generation of videos from images with specified starting and ending images.
|
||||
- Training the model based on token lengths. This allows for the implementation of various sizes and resolutions within the same model.
|
||||
|
||||
## InPaint Model
|
||||
We used [CogVideoX](https://github.com/THUDM/CogVideo/) as the foundational structure, referencing [EasyAnimate](https://github.com/aigc-apps/EasyAnimate) for the model training to generate videos from images.
|
||||
|
||||
During video generation, the **reference video** is encoded using VAE, with the **black area in the above image representing the part to be reconstructed, and the white area representing the start image**. This is stacked with noise latents and input into the Transformer for video generation. We perform 3D resizing on the **masked area**, directly resizing it to fit the canvas size of the video that needs reconstruction.
|
||||
|
||||
Then, we concatenate the latent, the encoded reference video, and the masked area, inputting them into DiT for noise prediction to obtain the final video.
|
||||
The pipeline structure of CogVideoX FUN is as follows:
|
||||
<img src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/pipeline.jpg" alt="ui" style="zoom:50%;" />
|
||||
|
||||
## Token Length-Based Model Training
|
||||
We collected approximately 1.2 million high-quality data for the training of CogVideoX-Fun. During the training, we resized the videos based on different token lengths. The entire training process is divided into three phases, with each phase corresponding to 13312 (for 512x512x49 videos), 29952 (for 768x768x49 videos), and 53248 (for 1024x1024x49 videos).
|
||||
|
||||
Taking CogVideoX-Fun-2B as an example:
|
||||
- In the 13312 phase, the batch size is 128 with 7k training steps.
|
||||
- In the 29952 phase, the batch size is 256 with 6.5k training steps.
|
||||
- In the 53248 phase, the batch size is 128 with 5k training steps.
|
||||
|
||||
During training, we combined high and low resolutions, enabling the model to support video generation from any resolution between 512 and 1280. For example, with a token length of 13312:
|
||||
- At a resolution of 512x512, the number of video frames is 49.
|
||||
- At a resolution of 768x768, the number of video frames is 21.
|
||||
- At a resolution of 1024x1024, the number of video frames is 9.
|
||||
|
||||
These resolutions and corresponding lengths were mixed for training, allowing the model to generate videos at different resolutions.
|
||||
|
||||
## Resize 3D Embedding
|
||||
In adapting CogVideoX-2B to the CogVideoX-Fun framework, it was found that the source code obtains 3D embeddings in a truncated manner. This approach only accommodates a single resolution; when the resolution changes, the embedding should also change.
|
||||
<img src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/PE_Interpolation.jpg" alt="ui" style="zoom:50%;" />
|
||||
|
||||
Referencing Pixart-Sigma, the above image is from the Pixart-Sigma paper. We used Positional Embeddings Interpolation (PE Interpolation) to resize 3D embeddings. PE Interpolation is more conducive to convergence than directly generating cosine and sine embeddings for different resolutions.
|
||||
@@ -0,0 +1,43 @@
|
||||
# CogVideoX FUN v1 Report
|
||||
|
||||
在CogVideoX-FUN中,我们基于CogVideoX在大约1.2m的数据上进行了训练,支持图片与视频预测,支持像素值从512x512x49、768x768x49、1024x1024x49与不同纵横比的视频生成。另外,我们支持图像到视频的生成与视频到视频的重建。
|
||||
|
||||
对比与CogVideoX,CogVideoX FUN还突出了以下功能:
|
||||
|
||||
- 引入InPaint模型,实现图生视频功能,可以通过首尾图指定视频生成。
|
||||
- 基于Token长度的模型训练。达成不同大小多分辨率在同一模型中的实现。
|
||||
|
||||
## InPaint模型
|
||||
我们以[CogVideoX](https://github.com/THUDM/CogVideo/)作为基础结构,参考[EasyAnimate](https://github.com/aigc-apps/EasyAnimate)进行图生视频的模型训练。
|
||||
|
||||
在进行视频生成的时候,将**参考视频**使用VAE进行encode,**上图黑色的部分代表需要重建的部分,白色的部分代表首图**,与噪声Latents一起堆叠后输入到Transformer中进行视频生成。
|
||||
|
||||
我们对**被Mask的区域**进行3D Resize,直接Resize到需要重建的视频的画布大小。
|
||||
|
||||
然后将Latent、Encode后的参考视频、被Mask的区域,concat后输入到DiT中进行噪声预测。获得最终的视频。
|
||||
|
||||
CogVideoX FUN的Pipeline结构如下:
|
||||
<img src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/pipeline.jpg" alt="ui" style="zoom:50%;" />
|
||||
|
||||
## 基于Token长度的模型训练
|
||||
我们收集了大约高质量的1.2m数据进行CogVideoX-Fun的训练。
|
||||
|
||||
在进行训练时,我们根据不同Token长度,对视频进行缩放后进行训练。整个训练过程分为三个阶段,每个阶段的13312(对应512x512x49的视频),29952(对应768x768x49的视频),53248(对应1024x1024x49的视频)。
|
||||
|
||||
以CogVideoX-Fun-2B为例子,其中:
|
||||
- 13312阶段,Batch size为128,训练步数为7k
|
||||
- 29952阶段,Batch size为256,训练步数为6.5k。
|
||||
- 53248阶段,Batch size为128,训练步数为5k。
|
||||
|
||||
训练时我们采用高低分辨率结合训练,因此模型支持从512到1280任意分辨率的视频生成,以13312 token长度为例:
|
||||
- 在512x512分辨率下,视频帧数为49;
|
||||
- 在768x768分辨率下,视频帧数为21;
|
||||
- 在1024x1024分辨率下,视频帧数为9;
|
||||
这些分辨率与对应长度混合训练,模型可以完成不同大小分辨率的视频生成。
|
||||
|
||||
## Resize 3D Embedding
|
||||
在适配CogVideoX-2B到CogVideoX-Fun框架的途中,发现源码是以截断的方式去得到3D Embedding的,这样的方式只能适配单一分辨率,当分辨率发生变化时,Embedding也应当发生变化。
|
||||
|
||||
<img src="https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/PE_Interpolation.jpg" alt="ui" style="zoom:50%;" />
|
||||
|
||||
参考Pixart-Sigma,上图来自于Pixart-Sigma论文,我们采用Positional Embeddings Interpolation(PE Interpolation)对3D embedding进行Resize,PE Interpolation相比于直接生成不同分辨率的Cos Sin Embedding更易收敛。
|
||||
+13
-11
@@ -20,8 +20,8 @@ import gc
|
||||
import logging
|
||||
import math
|
||||
import os
|
||||
import shutil
|
||||
import pickle
|
||||
import shutil
|
||||
import sys
|
||||
|
||||
import accelerate
|
||||
@@ -35,10 +35,10 @@ from accelerate import Accelerator
|
||||
from accelerate.logging import get_logger
|
||||
from accelerate.state import AcceleratorState
|
||||
from accelerate.utils import ProjectConfiguration, set_seed
|
||||
from diffusers import AutoencoderKL, DDPMScheduler, AutoencoderKLCogVideoX
|
||||
from diffusers import AutoencoderKL, DDPMScheduler
|
||||
from diffusers.models.embeddings import get_3d_rotary_pos_embed
|
||||
from diffusers.optimization import get_scheduler
|
||||
from diffusers.training_utils import EMAModel
|
||||
from diffusers.models.embeddings import get_3d_rotary_pos_embed
|
||||
from diffusers.utils import check_min_version, deprecate, is_wandb_available
|
||||
from diffusers.utils.import_utils import is_xformers_available
|
||||
from diffusers.utils.torch_utils import is_compiled_module
|
||||
@@ -64,16 +64,18 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from cogvideox.data.bucket_sampler import (ASPECT_RATIO_512,
|
||||
ASPECT_RATIO_RANDOM_CROP_512,
|
||||
ASPECT_RATIO_RANDOM_CROP_PROB,
|
||||
AspectRatioBatchImageVideoSampler,
|
||||
RandomSampler, get_closest_ratio)
|
||||
ASPECT_RATIO_RANDOM_CROP_512,
|
||||
ASPECT_RATIO_RANDOM_CROP_PROB,
|
||||
AspectRatioBatchImageVideoSampler,
|
||||
RandomSampler, get_closest_ratio)
|
||||
from cogvideox.data.dataset_image_video import (ImageVideoDataset,
|
||||
ImageVideoSampler,
|
||||
get_random_mask)
|
||||
ImageVideoSampler,
|
||||
get_random_mask)
|
||||
from cogvideox.models.autoencoder_magvit import AutoencoderKLCogVideoX
|
||||
from cogvideox.models.transformer3d import CogVideoXTransformer3DModel
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_Fun_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox_inpaint import CogVideoX_Fun_Pipeline_Inpaint
|
||||
from cogvideox.pipeline.pipeline_cogvideox_inpaint import \
|
||||
CogVideoX_Fun_Pipeline_Inpaint
|
||||
from cogvideox.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -1526,7 +1528,7 @@ def main():
|
||||
(grid_height, grid_width), base_size_width, base_size_height
|
||||
)
|
||||
freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
|
||||
embed_dim=transformer3d.config.attention_head_dim,
|
||||
embed_dim=unwrap_model(transformer3d).config.attention_head_dim,
|
||||
crops_coords=grid_crops_coords,
|
||||
grid_size=(grid_height, grid_width),
|
||||
temporal_size=num_frames,
|
||||
|
||||
@@ -36,7 +36,7 @@ from accelerate import Accelerator
|
||||
from accelerate.logging import get_logger
|
||||
from accelerate.state import AcceleratorState
|
||||
from accelerate.utils import ProjectConfiguration, set_seed
|
||||
from diffusers import AutoencoderKL, AutoencoderKLCogVideoX, DDPMScheduler
|
||||
from diffusers import AutoencoderKL, DDPMScheduler
|
||||
from diffusers.models.embeddings import get_3d_rotary_pos_embed
|
||||
from diffusers.optimization import get_scheduler
|
||||
from diffusers.training_utils import EMAModel
|
||||
@@ -70,14 +70,16 @@ from cogvideox.data.bucket_sampler import (ASPECT_RATIO_512,
|
||||
AspectRatioBatchImageVideoSampler,
|
||||
AspectRatioBatchSampler,
|
||||
RandomSampler, get_closest_ratio)
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_Fun_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox_inpaint import CogVideoX_Fun_Pipeline_Inpaint
|
||||
from cogvideox.data.dataset_image import CC15M
|
||||
from cogvideox.data.dataset_image_video import (ImageVideoDataset,
|
||||
ImageVideoSampler,
|
||||
get_random_mask)
|
||||
from cogvideox.data.dataset_video import VideoDataset, WebVid10M
|
||||
from cogvideox.models.autoencoder_magvit import AutoencoderKLCogVideoX
|
||||
from cogvideox.models.transformer3d import CogVideoXTransformer3DModel
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_Fun_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox_inpaint import \
|
||||
CogVideoX_Fun_Pipeline_Inpaint
|
||||
from cogvideox.utils.lora_utils import create_network, merge_lora, unmerge_lora
|
||||
from cogvideox.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
@@ -1480,7 +1482,7 @@ def main():
|
||||
(grid_height, grid_width), base_size_width, base_size_height
|
||||
)
|
||||
freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
|
||||
embed_dim=transformer3d.config.attention_head_dim,
|
||||
embed_dim=unwrap_model(transformer3d).config.attention_head_dim,
|
||||
crops_coords=grid_crops_coords,
|
||||
grid_size=(grid_height, grid_width),
|
||||
temporal_size=num_frames,
|
||||
|
||||
Reference in New Issue
Block a user