Rename && Update Readme
This commit is contained in:
 bubbliiiing
@@ -95,7 +95,6 @@ We need about 60GB available on disk (for saving weights), please check!
|
||||
#### b. Weights
|
||||
We'd better place the [weights](#model-zoo) along the specified path:
|
||||
|
||||
EasyAnimateV4:
|
||||
```
|
||||
📦 models/
|
||||
├── 📂 Diffusion_Transformer/
|
||||
@@ -111,7 +110,7 @@ EasyAnimateV4:
|
||||
#### a. Using Python Code
|
||||
- Step 1: Download the corresponding [weights](#model-zoo) and place them in the models folder.
|
||||
- Step 2: Modify prompt, neg_prompt, guidance_scale, and seed in the predict_t2v.py file.
|
||||
- Step 3: Run the predict_t2v.py file, wait for the generated results, and save the results in the samples/easyanimate-videos-t2v folder.
|
||||
- Step 3: Run the predict_t2v.py file, wait for the generated results, and save the results in the samples/cogvideox-fun-videos-t2v folder.
|
||||
- Step 4: If you want to combine other backbones you have trained with Lora, modify the predict_t2v.py and Lora_path in predict_t2v.py depending on the situation.
|
||||
|
||||
#### b. Using webui
|
||||
|
||||
+1
-1
@@ -109,7 +109,7 @@ Linux 的详细信息:
|
||||
##### i、运行python文件
|
||||
- 步骤1:下载对应[权重](#model-zoo)放入models文件夹。
|
||||
- 步骤2:在predict_t2v.py文件中修改prompt、neg_prompt、guidance_scale和seed。
|
||||
- 步骤3:运行predict_t2v.py文件,等待生成结果,结果保存在samples/cogvideox-videos-t2v文件夹中。
|
||||
- 步骤3:运行predict_t2v.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos-t2v文件夹中。
|
||||
- 步骤4:如果想结合自己训练的其他backbone与Lora,则看情况修改predict_t2v.py中的predict_t2v.py和lora_path。
|
||||
|
||||
##### ii、通过ui界面
|
||||
|
||||
@@ -38,11 +38,11 @@ EXAMPLE_DOC_STRING = """
|
||||
Examples:
|
||||
```python
|
||||
>>> import torch
|
||||
>>> from diffusers import CogVideoX_FUN_Pipeline
|
||||
>>> from diffusers import CogVideoX_Fun_Pipeline
|
||||
>>> from diffusers.utils import export_to_video
|
||||
|
||||
>>> # Models: "THUDM/CogVideoX-2b" or "THUDM/CogVideoX-5b"
|
||||
>>> pipe = CogVideoX_FUN_Pipeline.from_pretrained("THUDM/CogVideoX-2b", torch_dtype=torch.float16).to("cuda")
|
||||
>>> pipe = CogVideoX_Fun_Pipeline.from_pretrained("THUDM/CogVideoX-2b", torch_dtype=torch.float16).to("cuda")
|
||||
>>> prompt = (
|
||||
... "A panda, dressed in a small, red jacket and a tiny hat, sits on a wooden stool in a serene bamboo forest. "
|
||||
... "The panda's fluffy paws strum a miniature acoustic guitar, producing soft, melodic tunes. Nearby, a few other "
|
||||
@@ -137,7 +137,7 @@ def retrieve_timesteps(
|
||||
|
||||
|
||||
@dataclass
|
||||
class CogVideoX_FUN_PipelineOutput(BaseOutput):
|
||||
class CogVideoX_Fun_PipelineOutput(BaseOutput):
|
||||
r"""
|
||||
Output class for CogVideo pipelines.
|
||||
|
||||
@@ -151,9 +151,9 @@ class CogVideoX_FUN_PipelineOutput(BaseOutput):
|
||||
videos: torch.Tensor
|
||||
|
||||
|
||||
class CogVideoX_FUN_Pipeline(DiffusionPipeline):
|
||||
class CogVideoX_Fun_Pipeline(DiffusionPipeline):
|
||||
r"""
|
||||
Pipeline for text-to-video generation using CogVideoX_FUN.
|
||||
Pipeline for text-to-video generation using CogVideoX_Fun.
|
||||
|
||||
This model inherits from [`DiffusionPipeline`]. Check the superclass documentation for the generic methods the
|
||||
library implements for all the pipelines (such as downloading or saving, running on a particular device, etc.)
|
||||
@@ -511,7 +511,7 @@ class CogVideoX_FUN_Pipeline(DiffusionPipeline):
|
||||
] = None,
|
||||
callback_on_step_end_tensor_inputs: List[str] = ["latents"],
|
||||
max_sequence_length: int = 226,
|
||||
) -> Union[CogVideoX_FUN_PipelineOutput, Tuple]:
|
||||
) -> Union[CogVideoX_Fun_PipelineOutput, Tuple]:
|
||||
"""
|
||||
Function invoked when calling the pipeline for generation.
|
||||
|
||||
@@ -583,8 +583,8 @@ class CogVideoX_FUN_Pipeline(DiffusionPipeline):
|
||||
Examples:
|
||||
|
||||
Returns:
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_FUN_PipelineOutput`] or `tuple`:
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_FUN_PipelineOutput`] if `return_dict` is True, otherwise a
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_Fun_PipelineOutput`] or `tuple`:
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_Fun_PipelineOutput`] if `return_dict` is True, otherwise a
|
||||
`tuple`. When returning a tuple, the first element is a list with the generated images.
|
||||
"""
|
||||
|
||||
@@ -748,4 +748,4 @@ class CogVideoX_FUN_Pipeline(DiffusionPipeline):
|
||||
if not return_dict:
|
||||
video = torch.from_numpy(video)
|
||||
|
||||
return CogVideoX_FUN_PipelineOutput(videos=video)
|
||||
return CogVideoX_Fun_PipelineOutput(videos=video)
|
||||
|
||||
@@ -42,11 +42,11 @@ EXAMPLE_DOC_STRING = """
|
||||
Examples:
|
||||
```python
|
||||
>>> import torch
|
||||
>>> from diffusers import CogVideoX_FUN_Pipeline
|
||||
>>> from diffusers import CogVideoX_Fun_Pipeline
|
||||
>>> from diffusers.utils import export_to_video
|
||||
|
||||
>>> # Models: "THUDM/CogVideoX-2b" or "THUDM/CogVideoX-5b"
|
||||
>>> pipe = CogVideoX_FUN_Pipeline.from_pretrained("THUDM/CogVideoX-2b", torch_dtype=torch.float16).to("cuda")
|
||||
>>> pipe = CogVideoX_Fun_Pipeline.from_pretrained("THUDM/CogVideoX-2b", torch_dtype=torch.float16).to("cuda")
|
||||
>>> prompt = (
|
||||
... "A panda, dressed in a small, red jacket and a tiny hat, sits on a wooden stool in a serene bamboo forest. "
|
||||
... "The panda's fluffy paws strum a miniature acoustic guitar, producing soft, melodic tunes. Nearby, a few other "
|
||||
@@ -178,7 +178,7 @@ def resize_mask(mask, latent, process_first_frame_only=True):
|
||||
|
||||
|
||||
@dataclass
|
||||
class CogVideoX_FUN_PipelineOutput(BaseOutput):
|
||||
class CogVideoX_Fun_PipelineOutput(BaseOutput):
|
||||
r"""
|
||||
Output class for CogVideo pipelines.
|
||||
|
||||
@@ -192,7 +192,7 @@ class CogVideoX_FUN_PipelineOutput(BaseOutput):
|
||||
videos: torch.Tensor
|
||||
|
||||
|
||||
class CogVideoX_FUN_Pipeline_Inpaint(DiffusionPipeline):
|
||||
class CogVideoX_Fun_Pipeline_Inpaint(DiffusionPipeline):
|
||||
r"""
|
||||
Pipeline for text-to-video generation using CogVideoX.
|
||||
|
||||
@@ -203,7 +203,7 @@ class CogVideoX_FUN_Pipeline_Inpaint(DiffusionPipeline):
|
||||
vae ([`AutoencoderKL`]):
|
||||
Variational Auto-Encoder (VAE) Model to encode and decode videos to and from latent representations.
|
||||
text_encoder ([`T5EncoderModel`]):
|
||||
Frozen text-encoder. CogVideoX_FUN uses
|
||||
Frozen text-encoder. CogVideoX_Fun uses
|
||||
[T5](https://huggingface.co/docs/transformers/model_doc/t5#transformers.T5EncoderModel); specifically the
|
||||
[t5-v1_1-xxl](https://huggingface.co/PixArt-alpha/PixArt-alpha/tree/main/t5-v1_1-xxl) variant.
|
||||
tokenizer (`T5Tokenizer`):
|
||||
@@ -651,7 +651,7 @@ class CogVideoX_FUN_Pipeline_Inpaint(DiffusionPipeline):
|
||||
max_sequence_length: int = 226,
|
||||
strength: float = 1,
|
||||
comfyui_progressbar: bool = False,
|
||||
) -> Union[CogVideoX_FUN_PipelineOutput, Tuple]:
|
||||
) -> Union[CogVideoX_Fun_PipelineOutput, Tuple]:
|
||||
"""
|
||||
Function invoked when calling the pipeline for generation.
|
||||
|
||||
@@ -669,7 +669,7 @@ class CogVideoX_FUN_Pipeline_Inpaint(DiffusionPipeline):
|
||||
The width in pixels of the generated image. This is set to 1024 by default for the best results.
|
||||
num_frames (`int`, defaults to `48`):
|
||||
Number of frames to generate. Must be divisible by self.vae_scale_factor_temporal. Generated video will
|
||||
contain 1 extra frame because CogVideoX_FUN is conditioned with (num_seconds * fps + 1) frames where
|
||||
contain 1 extra frame because CogVideoX_Fun is conditioned with (num_seconds * fps + 1) frames where
|
||||
num_seconds is 6 and fps is 4. However, since videos can be saved at any fps, the only condition that
|
||||
needs to be satisfied is that of divisibility mentioned above.
|
||||
num_inference_steps (`int`, *optional*, defaults to 50):
|
||||
@@ -723,8 +723,8 @@ class CogVideoX_FUN_Pipeline_Inpaint(DiffusionPipeline):
|
||||
Examples:
|
||||
|
||||
Returns:
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_FUN_PipelineOutput`] or `tuple`:
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_FUN_PipelineOutput`] if `return_dict` is True, otherwise a
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_Fun_PipelineOutput`] or `tuple`:
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_Fun_PipelineOutput`] if `return_dict` is True, otherwise a
|
||||
`tuple`. When returning a tuple, the first element is a list with the generated images.
|
||||
"""
|
||||
|
||||
@@ -1000,4 +1000,4 @@ class CogVideoX_FUN_Pipeline_Inpaint(DiffusionPipeline):
|
||||
if not return_dict:
|
||||
video = torch.from_numpy(video)
|
||||
|
||||
return CogVideoX_FUN_PipelineOutput(videos=video)
|
||||
return CogVideoX_Fun_PipelineOutput(videos=video)
|
||||
|
||||
+6
-6
@@ -29,9 +29,9 @@ from transformers import (CLIPImageProcessor, CLIPVisionModelWithProjection,
|
||||
from cogvideox.data.bucket_sampler import ASPECT_RATIO_512, get_closest_ratio
|
||||
from ..models.autoencoder_magvit import AutoencoderKLCogVideoX
|
||||
from cogvideox.models.transformer3d import CogVideoXTransformer3DModel
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_FUN_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_Fun_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox_inpaint import \
|
||||
CogVideoX_FUN_Pipeline_Inpaint
|
||||
CogVideoX_Fun_Pipeline_Inpaint
|
||||
from cogvideox.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from cogvideox.utils.utils import (
|
||||
get_image_to_video_latent, get_video_to_video_latent,
|
||||
@@ -119,7 +119,7 @@ class CogVideoX_I2VController:
|
||||
|
||||
# Get pipeline
|
||||
if self.transformer.config.in_channels != self.vae.config.latent_channels:
|
||||
self.pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
|
||||
self.pipeline = CogVideoX_Fun_Pipeline_Inpaint.from_pretrained(
|
||||
diffusion_transformer_dropdown,
|
||||
vae=self.vae,
|
||||
transformer=self.transformer,
|
||||
@@ -127,7 +127,7 @@ class CogVideoX_I2VController:
|
||||
torch_dtype=self.weight_dtype
|
||||
)
|
||||
else:
|
||||
self.pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
|
||||
self.pipeline = CogVideoX_Fun_Pipeline.from_pretrained(
|
||||
diffusion_transformer_dropdown,
|
||||
vae=self.vae,
|
||||
transformer=self.transformer,
|
||||
@@ -673,7 +673,7 @@ class CogVideoX_I2VController_Modelscope:
|
||||
|
||||
# Get pipeline
|
||||
if self.transformer.config.in_channels != self.vae.config.latent_channels:
|
||||
self.pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
|
||||
self.pipeline = CogVideoX_Fun_Pipeline_Inpaint.from_pretrained(
|
||||
model_name,
|
||||
vae=self.vae,
|
||||
transformer=self.transformer,
|
||||
@@ -681,7 +681,7 @@ class CogVideoX_I2VController_Modelscope:
|
||||
torch_dtype=self.weight_dtype
|
||||
)
|
||||
else:
|
||||
self.pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
|
||||
self.pipeline = CogVideoX_Fun_Pipeline.from_pretrained(
|
||||
model_name,
|
||||
vae=self.vae,
|
||||
transformer=self.transformer,
|
||||
|
||||
+27
-51
@@ -1,16 +1,9 @@
|
||||
# ComfyUI EasyAnimate
|
||||
Easily use EasyAnimate inside ComfyUI!
|
||||
|
||||
[](https://arxiv.org/abs/2405.18991)
|
||||
[](https://easyanimate.github.io/)
|
||||
[](https://modelscope.cn/studios/PAI/EasyAnimate/summary)
|
||||
[](https://huggingface.co/spaces/alibaba-pai/EasyAnimate)
|
||||
# ComfyUI CogVideoX-Fun
|
||||
Easily use CogVideoX-Fun inside ComfyUI!
|
||||
|
||||
- [Installation](#1-installation)
|
||||
- [Node types](#node-types)
|
||||
- [Example workflows](#example-workflows)
|
||||
- [Image to video](#image-to-video)
|
||||
- [Image to video generation (high FPS w/ frame interpolation)](#image-to-video-generation-high-fps-w-frame-interpolation)
|
||||
|
||||
## 1. Installation
|
||||
|
||||
@@ -18,72 +11,55 @@ Easily use EasyAnimate inside ComfyUI!
|
||||
TBD
|
||||
|
||||
### Option 2: Install manually
|
||||
The EasyAnimate repository needs to be placed at `ComfyUI/custom_nodes/EasyAnimate/`.
|
||||
The CogVideoX-Fun repository needs to be placed at `ComfyUI/custom_nodes/CogVideoX-Fun/`.
|
||||
|
||||
```
|
||||
cd ComfyUI/custom_nodes/
|
||||
|
||||
# Git clone the easyanimate itself
|
||||
git clone https://github.com/aigc-apps/EasyAnimate.git
|
||||
# Git clone the cogvideox_fun itself
|
||||
git clone https://github.com/aigc-apps/CogVideoX-Fun.git
|
||||
|
||||
# Git clone the video outout node
|
||||
git clone https://github.com/Kosinkadink/ComfyUI-VideoHelperSuite.git
|
||||
|
||||
cd EasyAnimate/
|
||||
cd CogVideoX-Fun/
|
||||
python install.py
|
||||
```
|
||||
|
||||
### 2. Download models into `ComfyUI/models/EasyAnimate/`
|
||||
### 2. Download models into `ComfyUI/models/CogVideoX-Fun/`
|
||||
|
||||
| Name | Type | Storage Space | Url | Hugging Face | Description |
|
||||
| EasyAnimateV4-XL-2-InP.tar | EasyAnimateV4 | 18.2GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/Diffusion_Transformer/EasyAnimateV4-XL-2-InP.tar) | [🤗Link](https://huggingface.co/alibaba-pai/EasyAnimateV4-XL-2-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 144 frames at a rate of 24 frames per second. |
|
||||
|
||||
<details>
|
||||
<summary>(Obsolete) EasyAnimateV3:</summary>
|
||||
|
||||
| Name | Type | Storage Space | Url | Hugging Face | Description |
|
||||
|--|--|--|--|--|--|
|
||||
| EasyAnimateV3-XL-2-InP-512x512.tar | EasyAnimateV3 | 18.2GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/Diffusion_Transformer/EasyAnimateV3-XL-2-InP-512x512.tar) | [🤗Link](https://huggingface.co/alibaba-pai/EasyAnimateV3-XL-2-InP-512x512) | EasyAnimateV3 official weights for 512x512 text and image to video resolution. Training with 144 frames and fps 24 |
|
||||
| EasyAnimateV3-XL-2-InP-768x768.tar | EasyAnimateV3 | 18.2GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/Diffusion_Transformer/EasyAnimateV3-XL-2-InP-768x768.tar) | [🤗Link](https://huggingface.co/alibaba-pai/EasyAnimateV3-XL-2-InP-768x768) | EasyAnimateV3 official weights for 768x768 text and image to video resolution. Training with 144 frames and fps 24 |
|
||||
| EasyAnimateV3-XL-2-InP-960x960.tar | EasyAnimateV3 | 18.2GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/Diffusion_Transformer/EasyAnimateV3-XL-2-InP-960x960.tar) | [🤗Link](https://huggingface.co/alibaba-pai/EasyAnimateV3-XL-2-InP-960x960) | EasyAnimateV3 official weights for 960x960 text and image to video resolution. Training with 144 frames and fps 24 |
|
||||
</details>
|
||||
| Name | Storage Space | Url | Hugging Face | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP.tar.gz | Before extraction:9.69 GB \/ After extraction: 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 144 frames at a rate of 24 frames per second. |
|
||||
|
||||
## Node types
|
||||
- **LoadEasyAnimateModel**
|
||||
- Loads the EasyAnimate model
|
||||
- **LoadCogVideoX_Fun_Model**
|
||||
- Loads the CogVideoX-Fun model
|
||||
- **TextBox**
|
||||
- Write the prompt for EasyAnimate model
|
||||
- **EasyAnimateI2VSampler**
|
||||
- EasyAnimate Sampler for Image to Video
|
||||
- **EasyAnimateT2VSampler**
|
||||
- EasyAnimate Sampler for Text to Video
|
||||
- **EasyAnimateV2VSampler**
|
||||
- EasyAnimate Sampler for Video to Video
|
||||
- Write the prompt for CogVideoX-Fun model
|
||||
- **CogVideoX_Fun_I2VSampler**
|
||||
- CogVideoX-Fun Sampler for Image to Video
|
||||
- **CogVideoX_Fun_T2VSampler**
|
||||
- CogVideoX-Fun Sampler for Text to Video
|
||||
- **CogVideoX_Fun_V2VSampler**
|
||||
- CogVideoX-Fun Sampler for Video to Video
|
||||
|
||||
## Example workflows
|
||||
|
||||
### Video to video generation
|
||||
Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/asset/v4/easyanimatev4_workflow_v2v.json) of the json:
|
||||
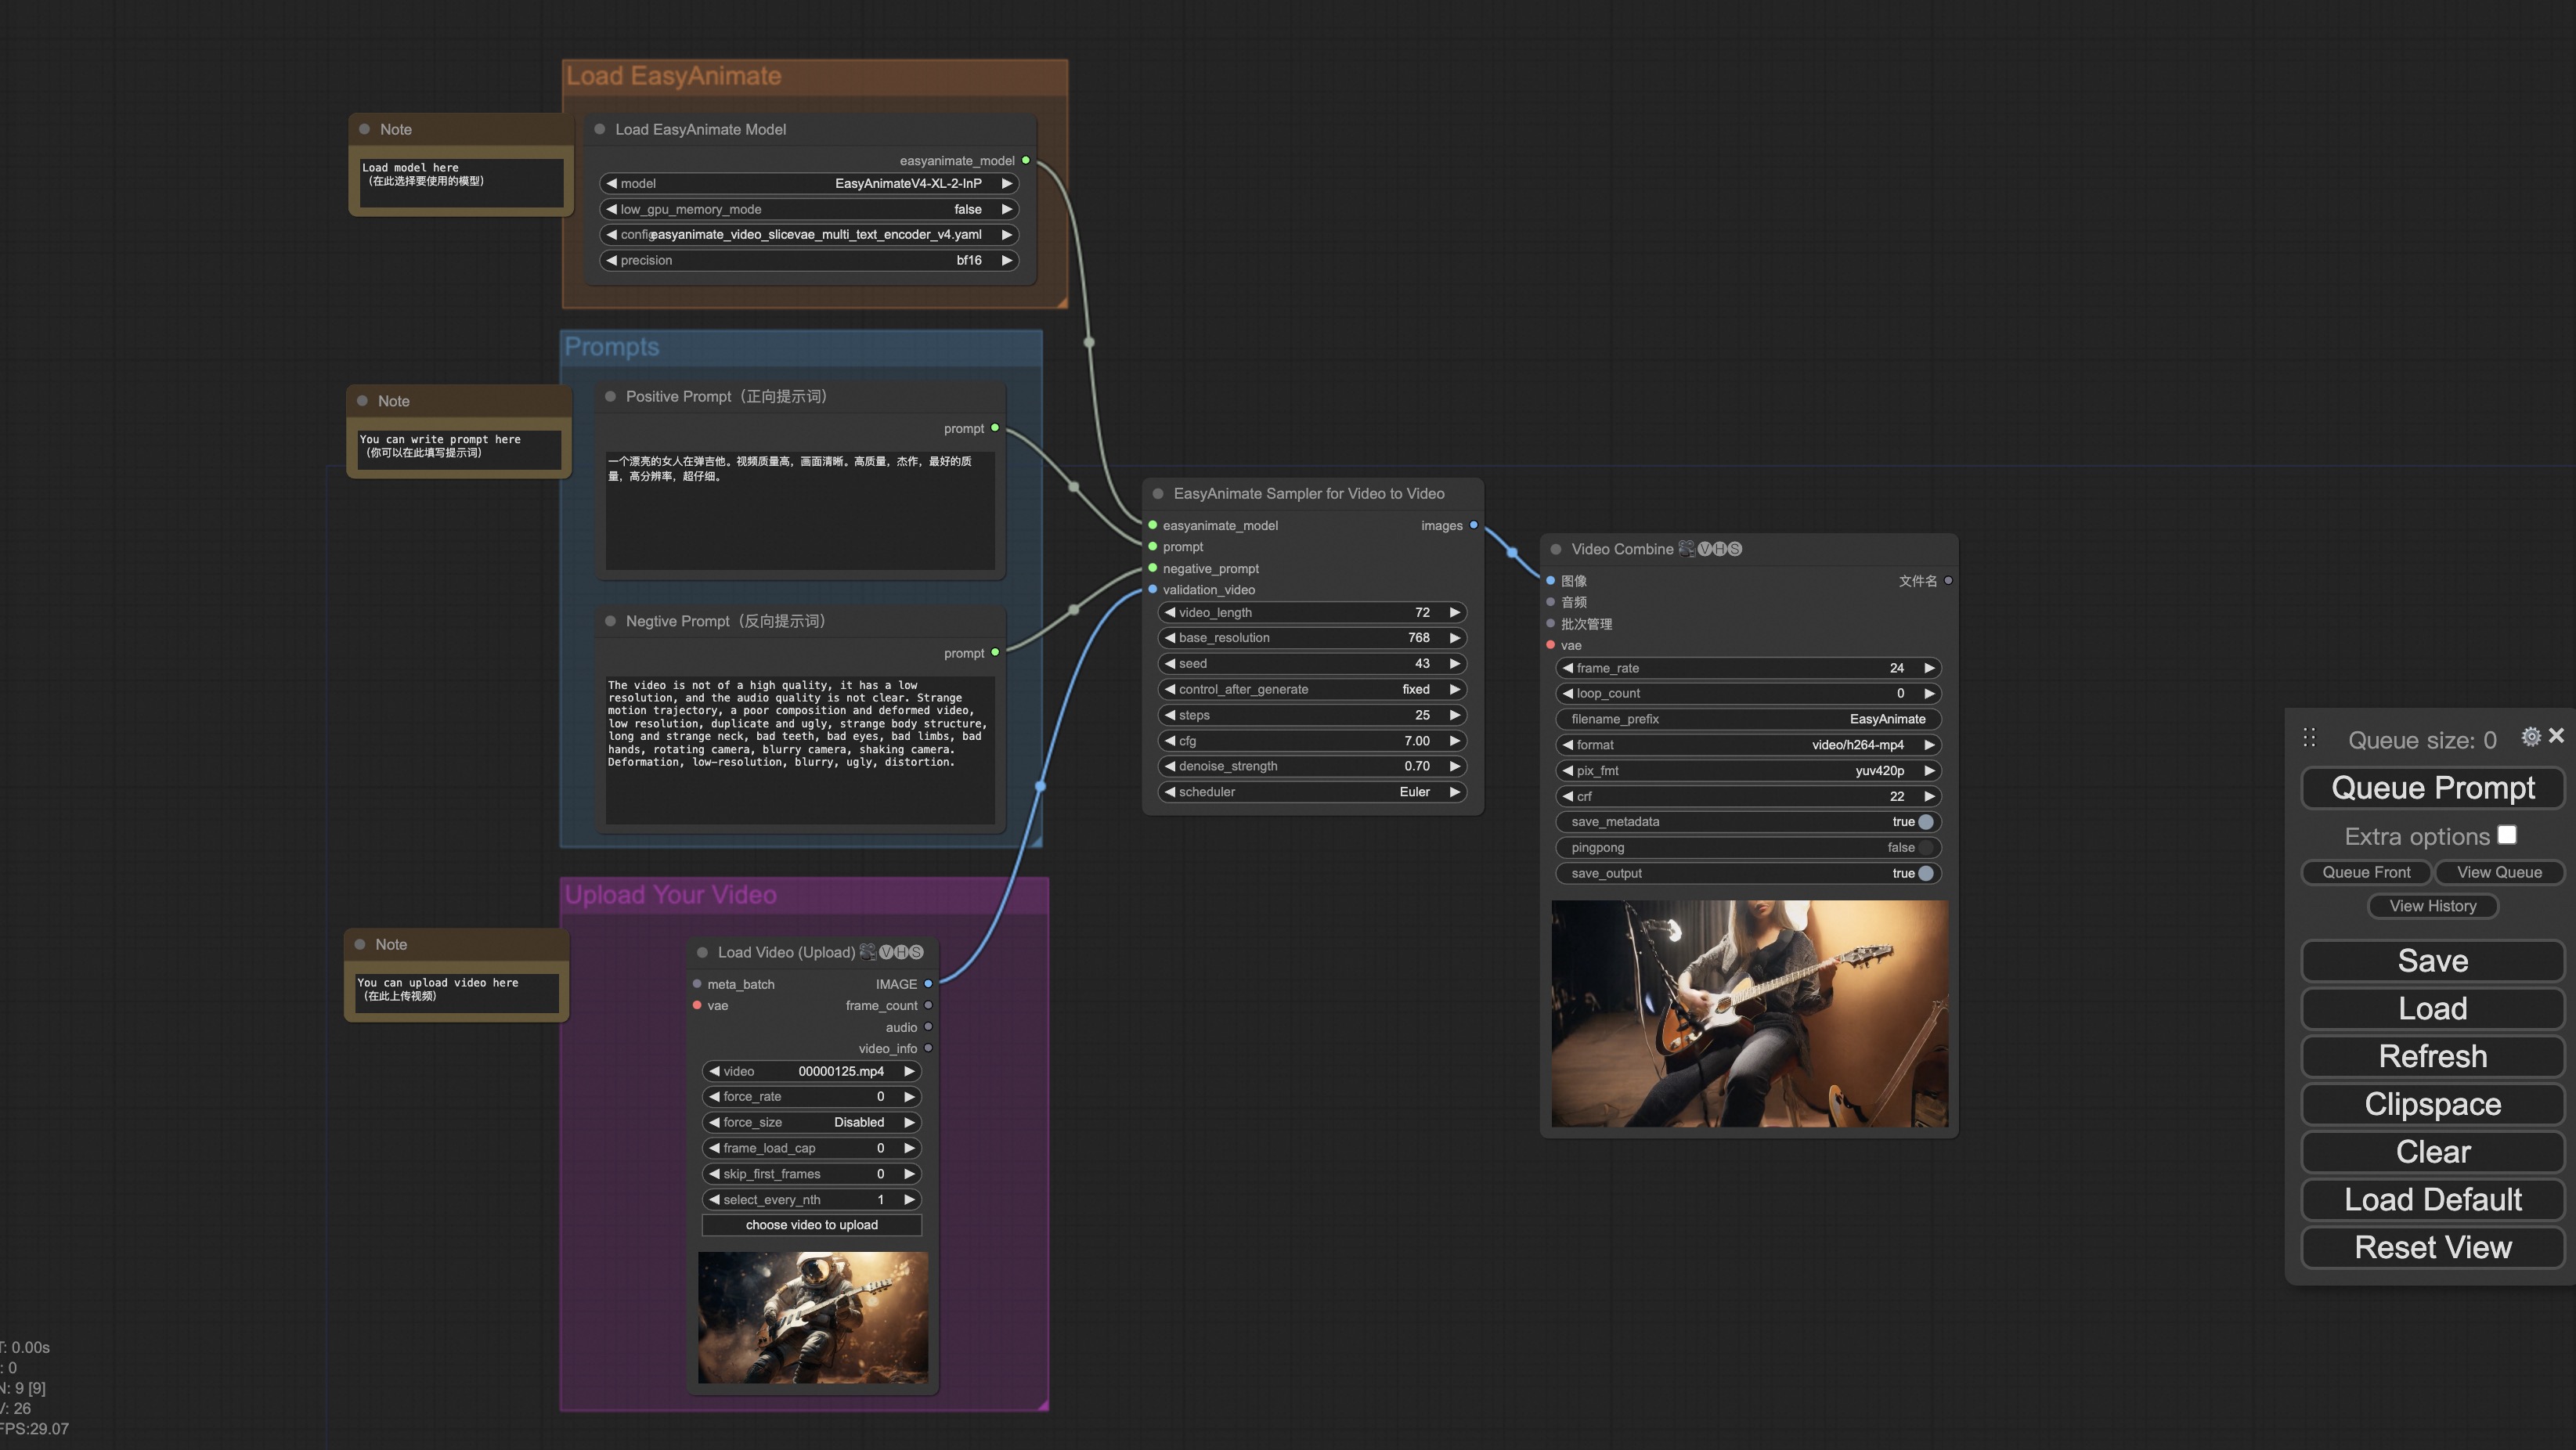
|
||||
Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/cogvideoxfunv1_workflow_v2v.json) of the json:
|
||||

|
||||
|
||||
You can run the demo using following video:
|
||||
[demo video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/asset/v4/play_guitar.mp4)
|
||||
[demo video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/play_guitar.mp4)
|
||||
|
||||
### Image to video generation
|
||||
Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/asset/v4/easyanimatev4_workflow_i2v.json) of the json:
|
||||
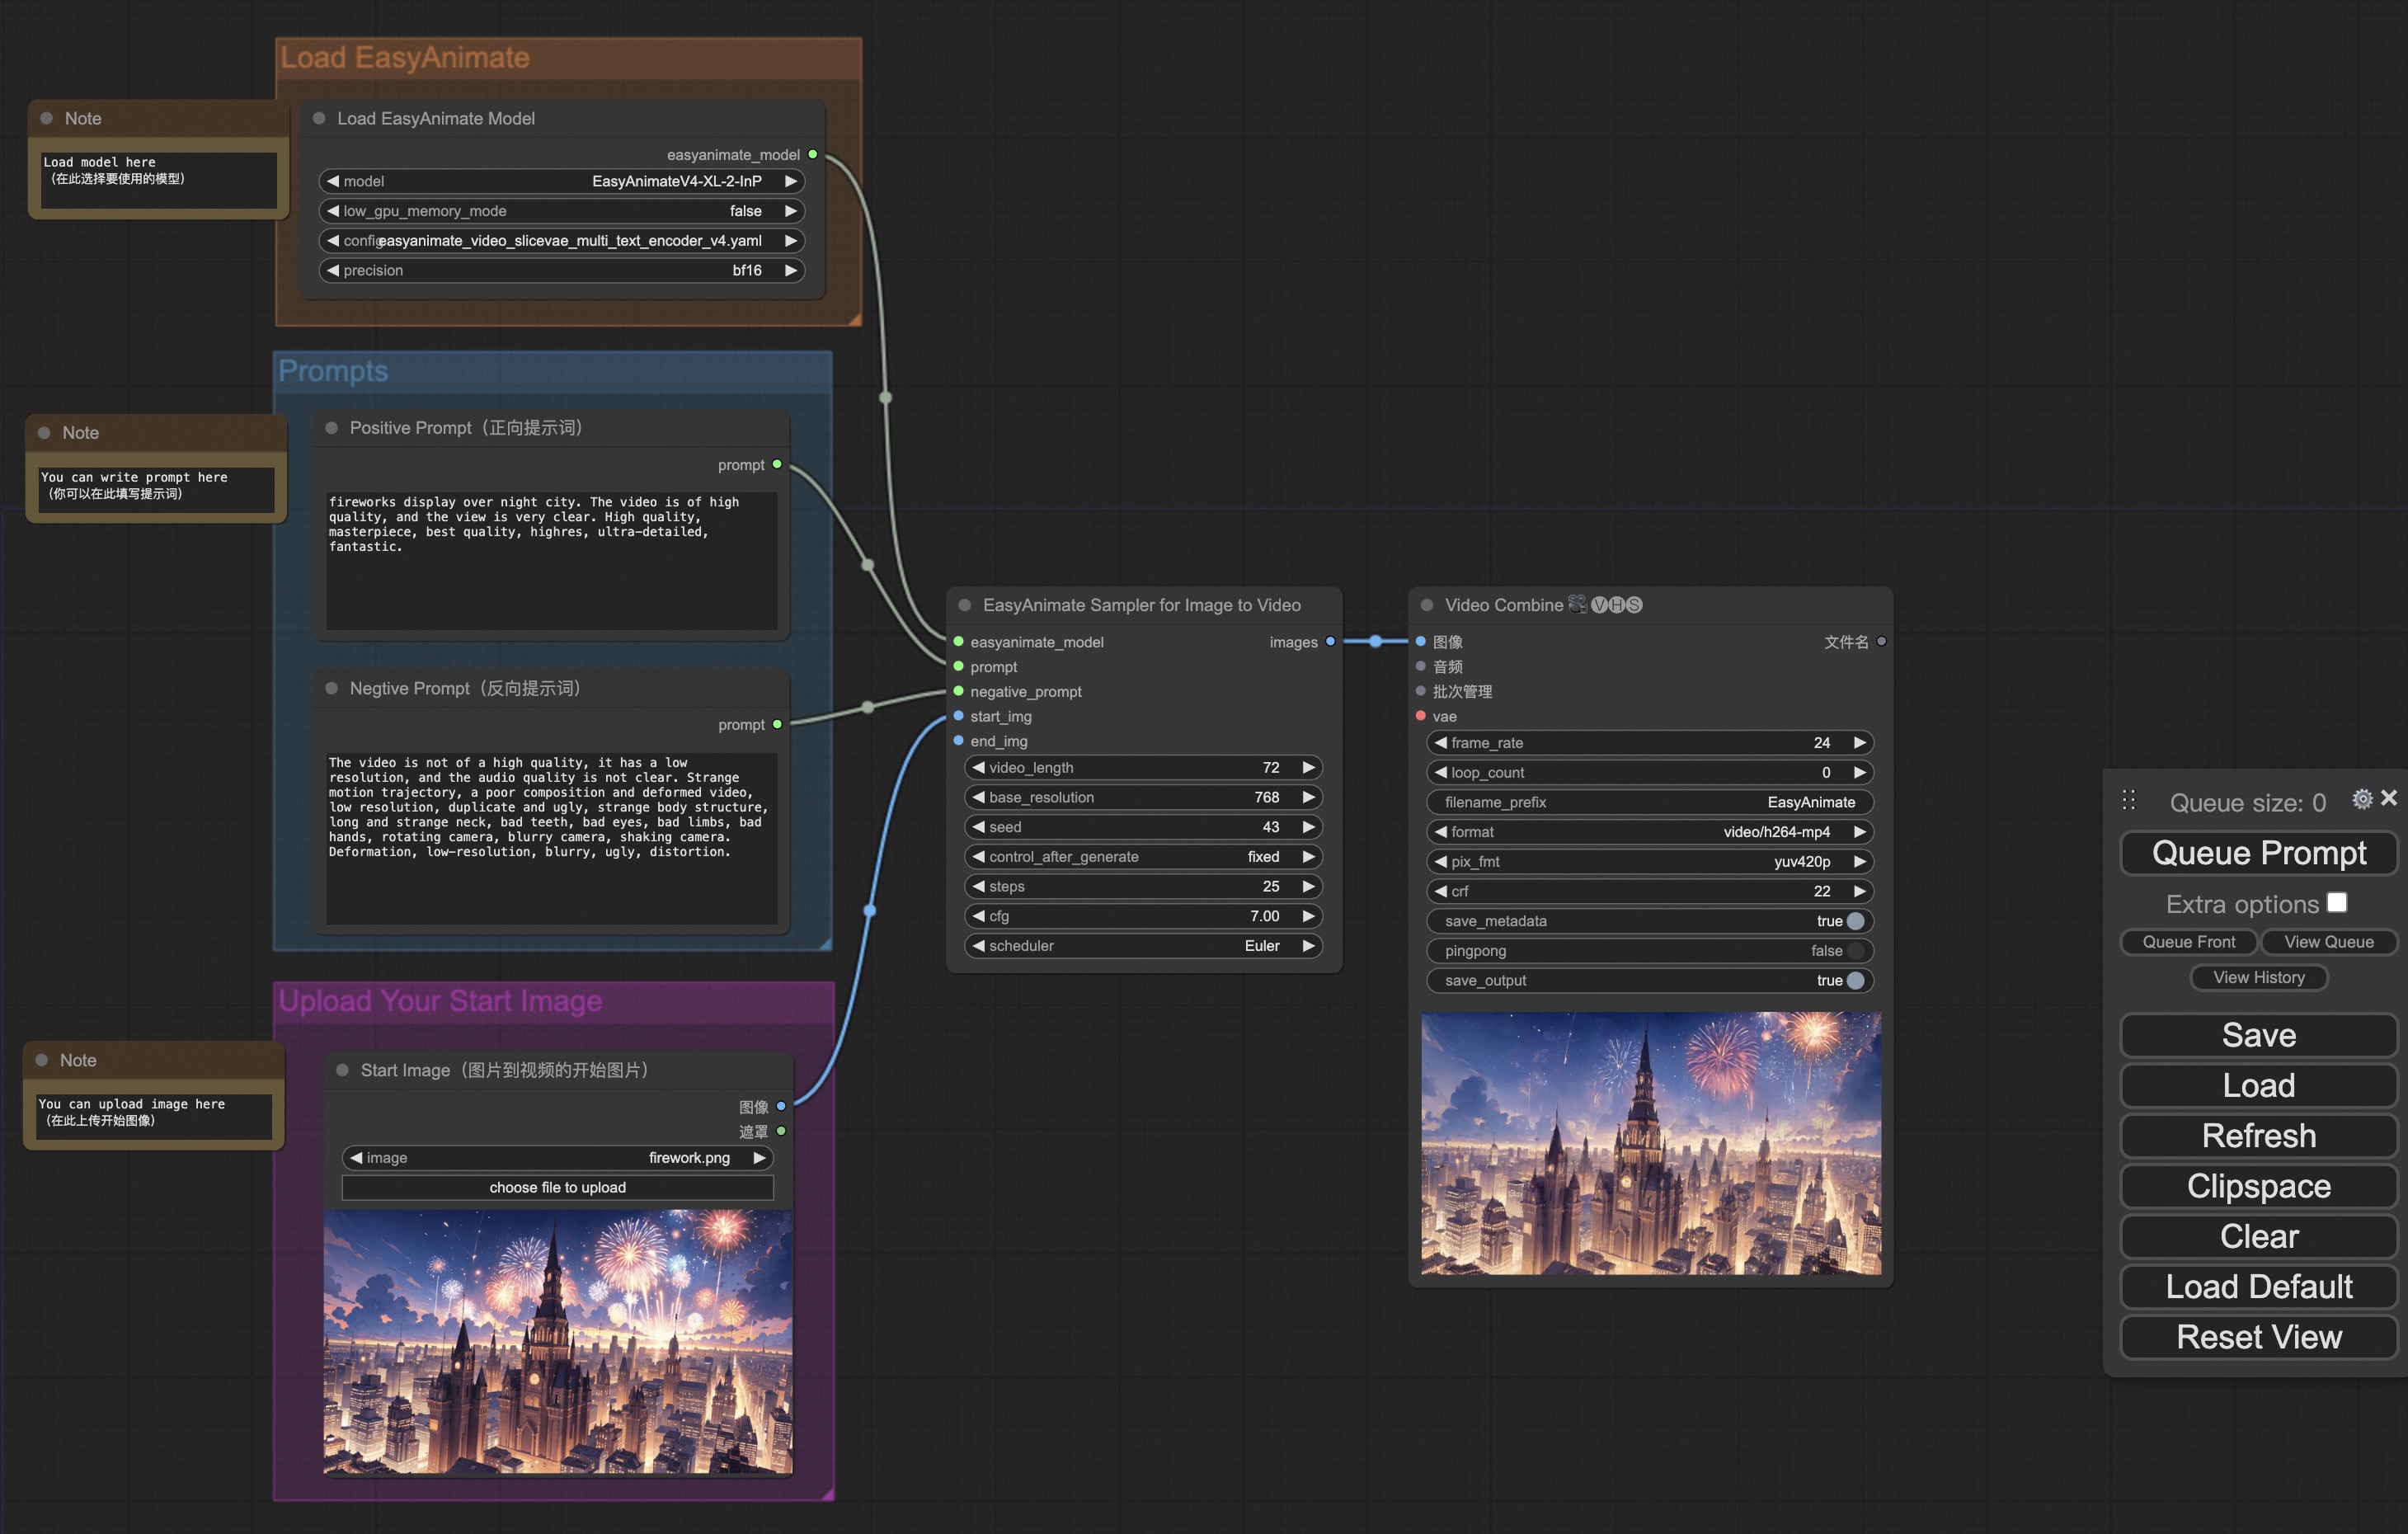
|
||||
Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/cogvideoxfunv1_workflow_i2v.json) of the json:
|
||||

|
||||
|
||||
You can run the demo using following photo:
|
||||
|
||||

|
||||
|
||||
### Text to video generation
|
||||
Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/asset/v4/easyanimatev4_workflow_t2v.json) of the json:
|
||||

|
||||
|
||||
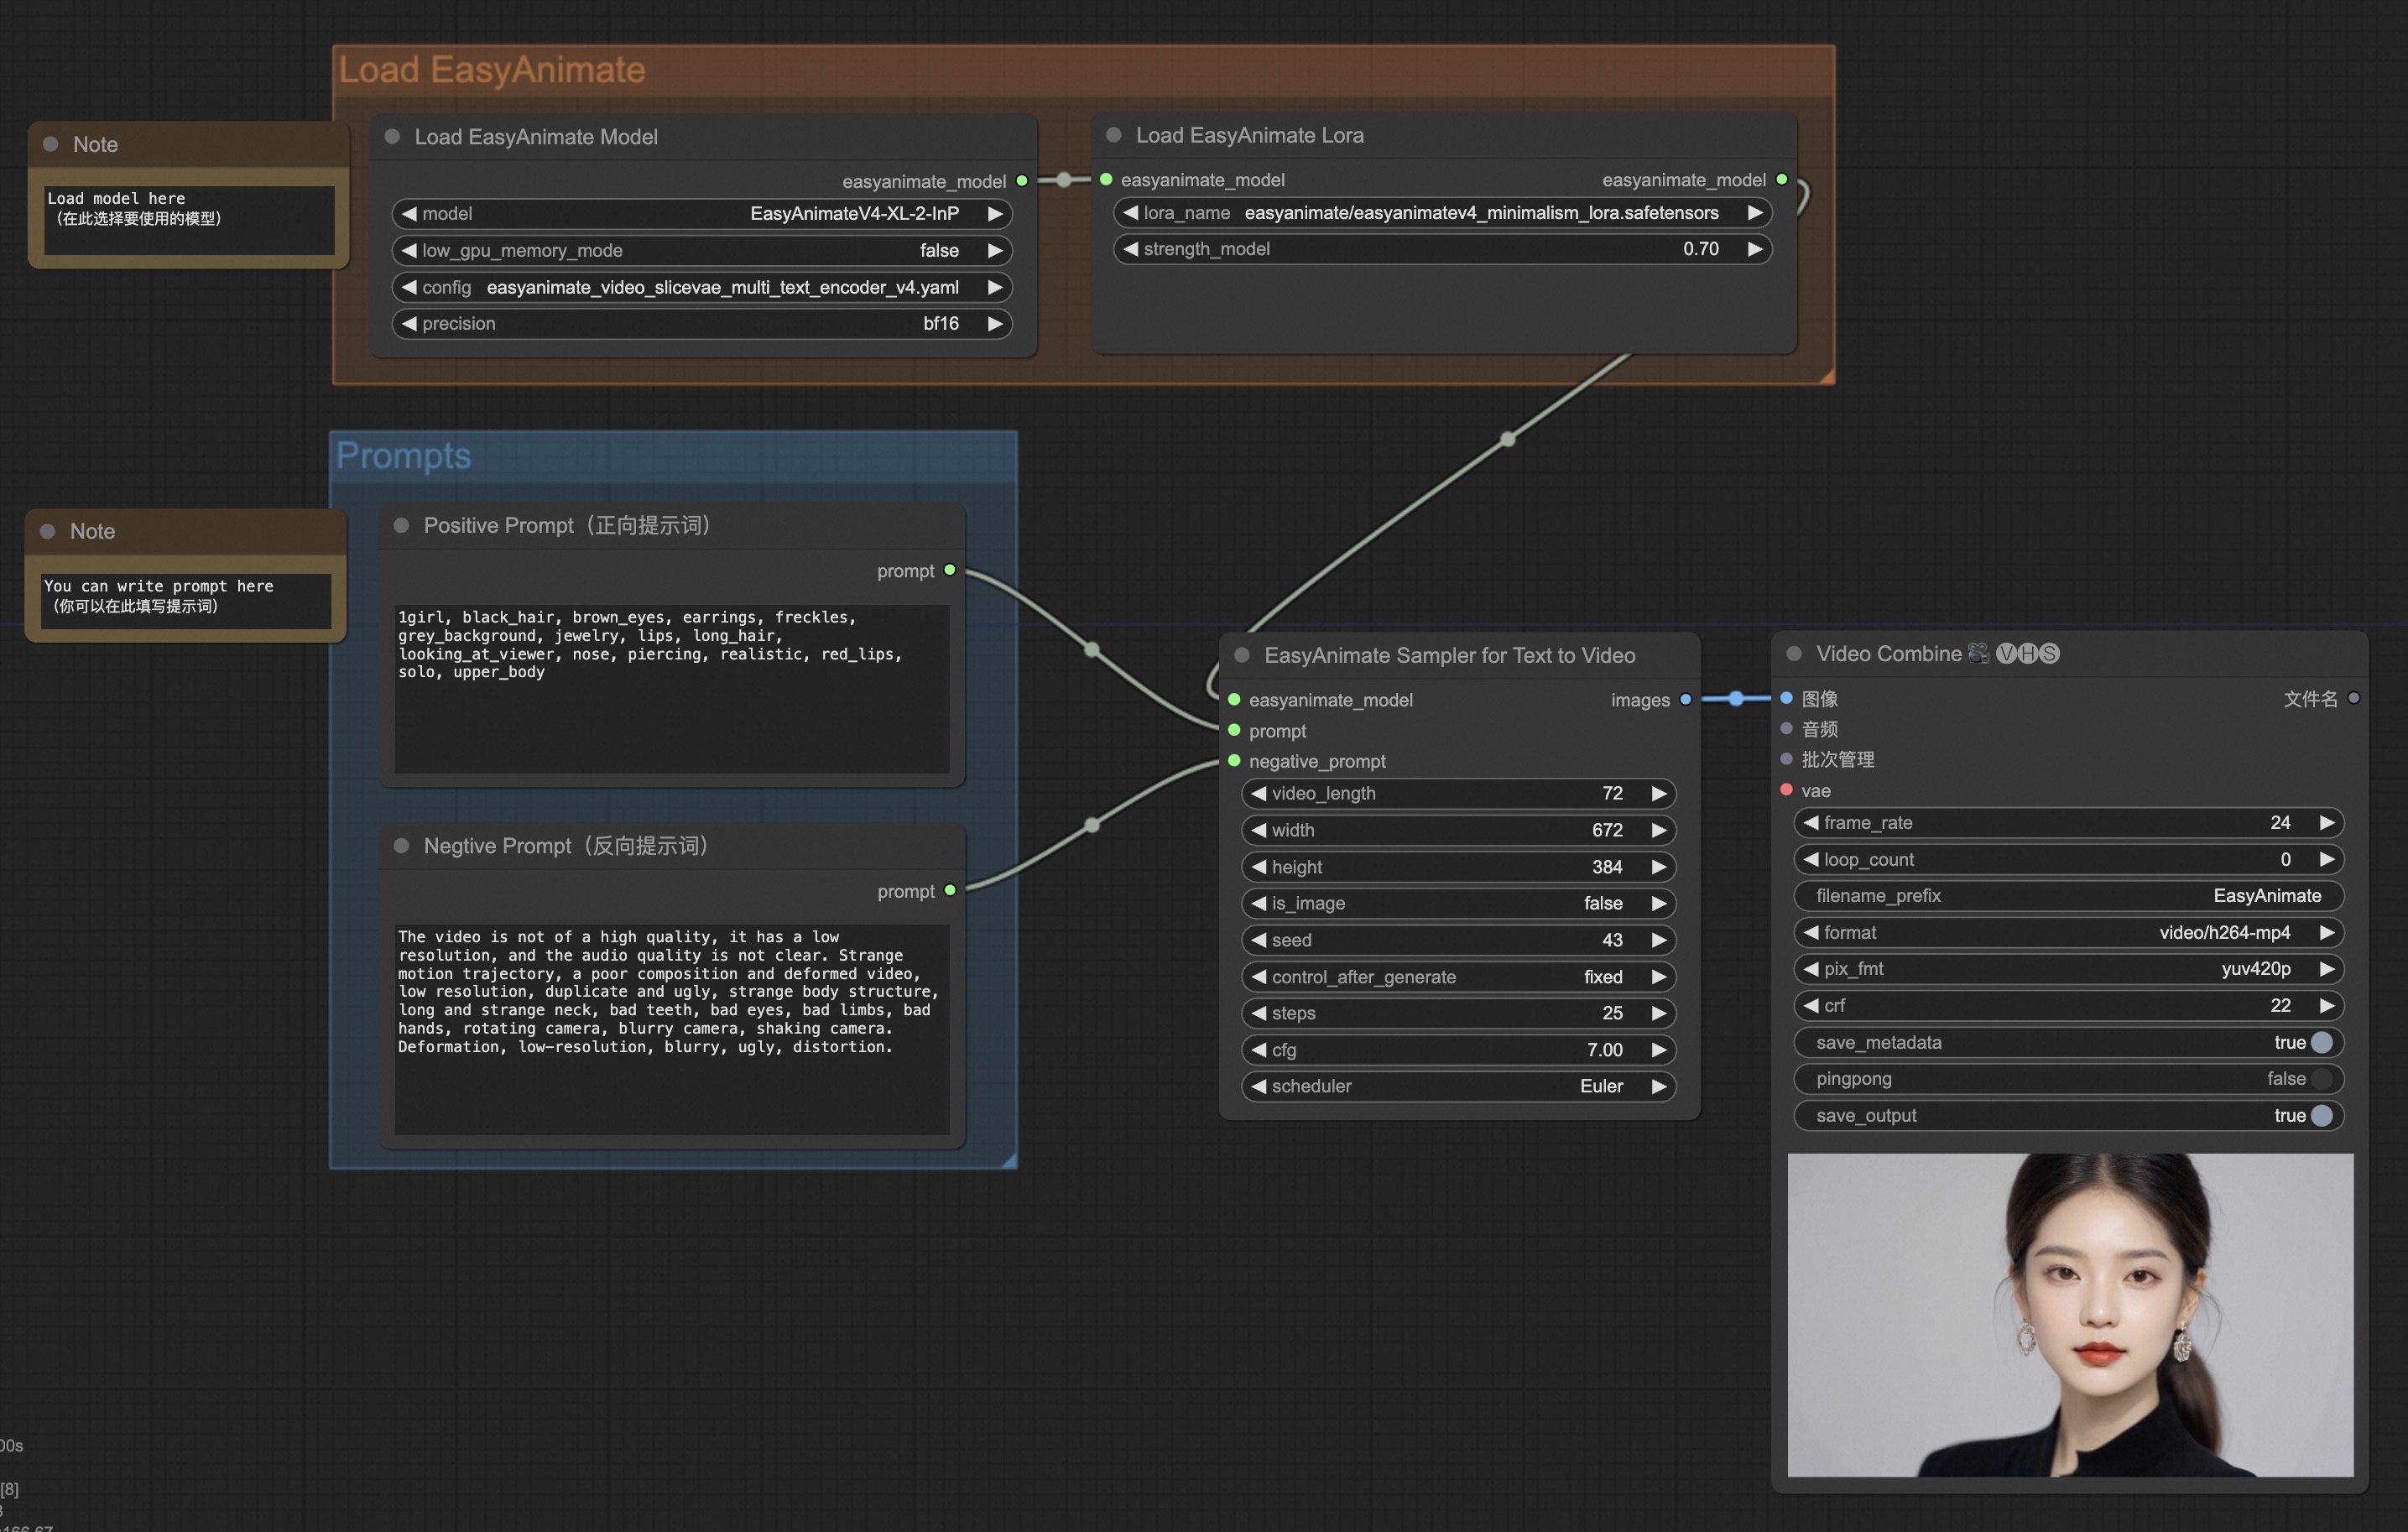
### Text to video generation With Lora
|
||||
We have provided a v4 version of the portrait Lora for testing, and the specific download link is [Lora download Link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/Personalized_Model/easyanimatev4_minimalism_lora.safetensors).
|
||||
|
||||
You can put this Lora at ```ComfyUI/models/loras/easyanimate```.
|
||||
|
||||
Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/easyanimate/asset/v4/easyanimatev4_workflow_lora.json) of the json:
|
||||
|
||||
Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/cogvideoxfunv1_workflow_t2v.json) of the json:
|
||||

|
||||
+21
-21
@@ -22,9 +22,9 @@ from transformers import T5EncoderModel, T5Tokenizer
|
||||
from ..cogvideox.data.bucket_sampler import ASPECT_RATIO_512, get_closest_ratio
|
||||
from ..cogvideox.models.autoencoder_magvit import AutoencoderKLCogVideoX
|
||||
from ..cogvideox.models.transformer3d import CogVideoXTransformer3DModel
|
||||
from ..cogvideox.pipeline.pipeline_cogvideox import CogVideoX_FUN_Pipeline
|
||||
from ..cogvideox.pipeline.pipeline_cogvideox import CogVideoX_Fun_Pipeline
|
||||
from ..cogvideox.pipeline.pipeline_cogvideox_inpaint import (
|
||||
CogVideoX_FUN_Pipeline_Inpaint)
|
||||
CogVideoX_Fun_Pipeline_Inpaint)
|
||||
from ..cogvideox.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from ..cogvideox.utils.utils import (get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
@@ -50,7 +50,7 @@ def to_pil(image):
|
||||
return numpy2pil(image)
|
||||
raise ValueError(f"Cannot convert {type(image)} to PIL.Image")
|
||||
|
||||
class LoadCogVideoX_FUN_Model:
|
||||
class LoadCogVideoX_Fun_Model:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
@@ -94,11 +94,11 @@ class LoadCogVideoX_FUN_Model:
|
||||
pbar = ProgressBar(3)
|
||||
|
||||
# Detect model is existing or not
|
||||
model_path = os.path.join(folder_paths.models_dir, "CogVideoX_FUN", model)
|
||||
model_path = os.path.join(folder_paths.models_dir, "CogVideoX_Fun", model)
|
||||
|
||||
if not os.path.exists(model_path):
|
||||
if os.path.exists(eas_cache_dir):
|
||||
model_path = os.path.join(eas_cache_dir, 'CogVideoX_FUN', model)
|
||||
model_path = os.path.join(eas_cache_dir, 'CogVideoX_Fun', model)
|
||||
else:
|
||||
print(f"Please download cogvideoxfun model to: {model_path}")
|
||||
|
||||
@@ -125,7 +125,7 @@ class LoadCogVideoX_FUN_Model:
|
||||
|
||||
# Get pipeline
|
||||
if transformer.config.in_channels != vae.config.latent_channels:
|
||||
pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
|
||||
pipeline = CogVideoX_Fun_Pipeline_Inpaint.from_pretrained(
|
||||
model_path,
|
||||
vae=vae,
|
||||
transformer=transformer,
|
||||
@@ -133,7 +133,7 @@ class LoadCogVideoX_FUN_Model:
|
||||
torch_dtype=weight_dtype
|
||||
)
|
||||
else:
|
||||
pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
|
||||
pipeline = CogVideoX_Fun_Pipeline.from_pretrained(
|
||||
model_path,
|
||||
vae=vae,
|
||||
transformer=transformer,
|
||||
@@ -154,7 +154,7 @@ class LoadCogVideoX_FUN_Model:
|
||||
}
|
||||
return (cogvideoxfun_model,)
|
||||
|
||||
class LoadCogVideoX_FUN_Lora:
|
||||
class LoadCogVideoX_Fun_Lora:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
@@ -200,7 +200,7 @@ class TextBox:
|
||||
def process(self, prompt):
|
||||
return (prompt, )
|
||||
|
||||
class CogVideoX_FUN_I2VSampler:
|
||||
class CogVideoX_Fun_I2VSampler:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
@@ -320,7 +320,7 @@ class CogVideoX_FUN_I2VSampler:
|
||||
return (videos,)
|
||||
|
||||
|
||||
class CogVideoX_FUN_T2VSampler:
|
||||
class CogVideoX_Fun_T2VSampler:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
@@ -435,7 +435,7 @@ class CogVideoX_FUN_T2VSampler:
|
||||
pipeline = unmerge_lora(pipeline, _lora_path, _lora_weight)
|
||||
return (videos,)
|
||||
|
||||
class CogVideoX_FUN_V2VSampler:
|
||||
class CogVideoX_Fun_V2VSampler:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
@@ -559,19 +559,19 @@ class CogVideoX_FUN_V2VSampler:
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"TextBox": TextBox,
|
||||
"LoadCogVideoX_FUN_Model": LoadCogVideoX_FUN_Model,
|
||||
"LoadCogVideoX_FUN_Lora": LoadCogVideoX_FUN_Lora,
|
||||
"CogVideoX_FUN_I2VSampler": CogVideoX_FUN_I2VSampler,
|
||||
"CogVideoX_FUN_T2VSampler": CogVideoX_FUN_T2VSampler,
|
||||
"CogVideoX_FUN_V2VSampler": CogVideoX_FUN_V2VSampler,
|
||||
"LoadCogVideoX_Fun_Model": LoadCogVideoX_Fun_Model,
|
||||
"LoadCogVideoX_Fun_Lora": LoadCogVideoX_Fun_Lora,
|
||||
"CogVideoX_Fun_I2VSampler": CogVideoX_Fun_I2VSampler,
|
||||
"CogVideoX_Fun_T2VSampler": CogVideoX_Fun_T2VSampler,
|
||||
"CogVideoX_Fun_V2VSampler": CogVideoX_Fun_V2VSampler,
|
||||
}
|
||||
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"TextBox": "TextBox",
|
||||
"LoadCogVideoX_FUN_Model": "Load CogVideoX-Fun Model",
|
||||
"LoadCogVideoX_FUN_Lora": "Load CogVideoX-Fun Lora",
|
||||
"CogVideoX_FUN_I2VSampler": "CogVideoX-Fun Sampler for Image to Video",
|
||||
"CogVideoX_FUN_T2VSampler": "CogVideoX-Fun Sampler for Text to Video",
|
||||
"CogVideoX_FUN_V2VSampler": "CogVideoX-Fun Sampler for Video to Video",
|
||||
"LoadCogVideoX_Fun_Model": "Load CogVideoX-Fun Model",
|
||||
"LoadCogVideoX_Fun_Lora": "Load CogVideoX-Fun Lora",
|
||||
"CogVideoX_Fun_I2VSampler": "CogVideoX-Fun Sampler for Image to Video",
|
||||
"CogVideoX_Fun_T2VSampler": "CogVideoX-Fun Sampler for Text to Video",
|
||||
"CogVideoX_Fun_V2VSampler": "CogVideoX-Fun Sampler for Video to Video",
|
||||
}
|
||||
@@ -115,7 +115,7 @@
|
||||
},
|
||||
{
|
||||
"id": 83,
|
||||
"type": "LoadCogVideoX_FUN_Model",
|
||||
"type": "LoadCogVideoX_Fun_Model",
|
||||
"pos": [
|
||||
300,
|
||||
-294
|
||||
@@ -139,7 +139,7 @@
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadCogVideoX_FUN_Model"
|
||||
"Node name for S&R": "LoadCogVideoX_Fun_Model"
|
||||
},
|
||||
"widgets_values": [
|
||||
"CogVideoX-Fun-2b-InP",
|
||||
@@ -215,7 +215,7 @@
|
||||
},
|
||||
{
|
||||
"id": 82,
|
||||
"type": "CogVideoX_FUN_I2VSampler",
|
||||
"type": "CogVideoX_Fun_I2VSampler",
|
||||
"pos": [
|
||||
758,
|
||||
93
|
||||
@@ -267,7 +267,7 @@
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "CogVideoX_FUN_I2VSampler"
|
||||
"Node name for S&R": "CogVideoX_Fun_I2VSampler"
|
||||
},
|
||||
"widgets_values": [
|
||||
49,
|
||||
|
||||
@@ -83,7 +83,7 @@
|
||||
},
|
||||
{
|
||||
"id": 87,
|
||||
"type": "LoadCogVideoX_FUN_Model",
|
||||
"type": "LoadCogVideoX_Fun_Model",
|
||||
"pos": [
|
||||
302,
|
||||
-285
|
||||
@@ -107,7 +107,7 @@
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadCogVideoX_FUN_Model"
|
||||
"Node name for S&R": "LoadCogVideoX_Fun_Model"
|
||||
},
|
||||
"widgets_values": [
|
||||
"CogVideoX-Fun-2b-InP",
|
||||
@@ -150,7 +150,7 @@
|
||||
},
|
||||
{
|
||||
"id": 88,
|
||||
"type": "CogVideoX_FUN_T2VSampler",
|
||||
"type": "CogVideoX_Fun_T2VSampler",
|
||||
"pos": [
|
||||
728,
|
||||
-68
|
||||
@@ -192,7 +192,7 @@
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "CogVideoX_FUN_T2VSampler"
|
||||
"Node name for S&R": "CogVideoX_Fun_T2VSampler"
|
||||
},
|
||||
"widgets_values": [
|
||||
49,
|
||||
|
||||
@@ -189,7 +189,7 @@
|
||||
},
|
||||
{
|
||||
"id": 88,
|
||||
"type": "LoadCogVideoX_FUN_Model",
|
||||
"type": "LoadCogVideoX_Fun_Model",
|
||||
"pos": [
|
||||
309,
|
||||
-286
|
||||
@@ -213,7 +213,7 @@
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadCogVideoX_FUN_Model"
|
||||
"Node name for S&R": "LoadCogVideoX_Fun_Model"
|
||||
},
|
||||
"widgets_values": [
|
||||
"CogVideoX-Fun-2b-InP",
|
||||
@@ -256,7 +256,7 @@
|
||||
},
|
||||
{
|
||||
"id": 87,
|
||||
"type": "CogVideoX_FUN_V2VSampler",
|
||||
"type": "CogVideoX_Fun_V2VSampler",
|
||||
"pos": [
|
||||
778,
|
||||
93
|
||||
@@ -304,7 +304,7 @@
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "CogVideoX_FUN_V2VSampler"
|
||||
"Node name for S&R": "CogVideoX_Fun_V2VSampler"
|
||||
},
|
||||
"widgets_values": [
|
||||
49,
|
||||
|
||||
+4
-4
@@ -15,8 +15,8 @@ from PIL import Image
|
||||
|
||||
from cogvideox.models.transformer3d import CogVideoXTransformer3DModel
|
||||
from cogvideox.models.autoencoder_magvit import AutoencoderKLCogVideoX
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_FUN_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox_inpaint import CogVideoX_FUN_Pipeline_Inpaint
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_Fun_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox_inpaint import CogVideoX_Fun_Pipeline_Inpaint
|
||||
from cogvideox.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from cogvideox.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
@@ -112,7 +112,7 @@ scheduler = Choosen_Scheduler.from_pretrained(
|
||||
)
|
||||
|
||||
if transformer.config.in_channels != vae.config.latent_channels:
|
||||
pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
|
||||
pipeline = CogVideoX_Fun_Pipeline_Inpaint.from_pretrained(
|
||||
model_name,
|
||||
vae=vae,
|
||||
text_encoder=text_encoder,
|
||||
@@ -121,7 +121,7 @@ if transformer.config.in_channels != vae.config.latent_channels:
|
||||
torch_dtype=weight_dtype
|
||||
)
|
||||
else:
|
||||
pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
|
||||
pipeline = CogVideoX_Fun_Pipeline.from_pretrained(
|
||||
model_name,
|
||||
vae=vae,
|
||||
text_encoder=text_encoder,
|
||||
|
||||
+4
-4
@@ -15,8 +15,8 @@ from PIL import Image
|
||||
|
||||
from cogvideox.models.transformer3d import CogVideoXTransformer3DModel
|
||||
from cogvideox.models.autoencoder_magvit import AutoencoderKLCogVideoX
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_FUN_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox_inpaint import CogVideoX_FUN_Pipeline_Inpaint
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_Fun_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox_inpaint import CogVideoX_Fun_Pipeline_Inpaint
|
||||
from cogvideox.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from cogvideox.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
@@ -103,7 +103,7 @@ scheduler = Choosen_Scheduler.from_pretrained(
|
||||
)
|
||||
|
||||
if transformer.config.in_channels != vae.config.latent_channels:
|
||||
pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
|
||||
pipeline = CogVideoX_Fun_Pipeline_Inpaint.from_pretrained(
|
||||
model_name,
|
||||
vae=vae,
|
||||
text_encoder=text_encoder,
|
||||
@@ -112,7 +112,7 @@ if transformer.config.in_channels != vae.config.latent_channels:
|
||||
torch_dtype=weight_dtype
|
||||
)
|
||||
else:
|
||||
pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
|
||||
pipeline = CogVideoX_Fun_Pipeline.from_pretrained(
|
||||
model_name,
|
||||
vae=vae,
|
||||
text_encoder=text_encoder,
|
||||
|
||||
+4
-4
@@ -15,9 +15,9 @@ from transformers import (CLIPImageProcessor, CLIPVisionModelWithProjection,
|
||||
|
||||
from cogvideox.models.autoencoder_magvit import AutoencoderKLCogVideoX
|
||||
from cogvideox.models.transformer3d import CogVideoXTransformer3DModel
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_FUN_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_Fun_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox_inpaint import \
|
||||
CogVideoX_FUN_Pipeline_Inpaint
|
||||
CogVideoX_Fun_Pipeline_Inpaint
|
||||
from cogvideox.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from cogvideox.utils.utils import get_video_to_video_latent, save_videos_grid
|
||||
|
||||
@@ -108,7 +108,7 @@ scheduler = Choosen_Scheduler.from_pretrained(
|
||||
)
|
||||
|
||||
if transformer.config.in_channels != vae.config.latent_channels:
|
||||
pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
|
||||
pipeline = CogVideoX_Fun_Pipeline_Inpaint.from_pretrained(
|
||||
model_name,
|
||||
vae=vae,
|
||||
text_encoder=text_encoder,
|
||||
@@ -117,7 +117,7 @@ if transformer.config.in_channels != vae.config.latent_channels:
|
||||
torch_dtype=weight_dtype
|
||||
)
|
||||
else:
|
||||
pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
|
||||
pipeline = CogVideoX_Fun_Pipeline.from_pretrained(
|
||||
model_name,
|
||||
vae=vae,
|
||||
text_encoder=text_encoder,
|
||||
|
||||
+4
-4
@@ -72,8 +72,8 @@ from cogvideox.data.dataset_image_video import (ImageVideoDataset,
|
||||
ImageVideoSampler,
|
||||
get_random_mask)
|
||||
from cogvideox.models.transformer3d import CogVideoXTransformer3DModel
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_FUN_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox_inpaint import CogVideoX_FUN_Pipeline_Inpaint
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_Fun_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox_inpaint import CogVideoX_Fun_Pipeline_Inpaint
|
||||
from cogvideox.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -163,7 +163,7 @@ def log_validation(vae, text_encoder, tokenizer, transformer3d, args, accelerato
|
||||
transformer3d_val.load_state_dict(accelerator.unwrap_model(transformer3d).state_dict())
|
||||
|
||||
if args.train_mode != "normal":
|
||||
pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
|
||||
pipeline = CogVideoX_Fun_Pipeline_Inpaint.from_pretrained(
|
||||
args.pretrained_model_name_or_path,
|
||||
vae=accelerator.unwrap_model(vae).to(weight_dtype),
|
||||
text_encoder=accelerator.unwrap_model(text_encoder),
|
||||
@@ -172,7 +172,7 @@ def log_validation(vae, text_encoder, tokenizer, transformer3d, args, accelerato
|
||||
torch_dtype=weight_dtype
|
||||
)
|
||||
else:
|
||||
pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
|
||||
pipeline = CogVideoX_Fun_Pipeline.from_pretrained(
|
||||
args.pretrained_model_name_or_path,
|
||||
vae=accelerator.unwrap_model(vae).to(weight_dtype),
|
||||
text_encoder=accelerator.unwrap_model(text_encoder),
|
||||
|
||||
@@ -70,8 +70,8 @@ from cogvideox.data.bucket_sampler import (ASPECT_RATIO_512,
|
||||
AspectRatioBatchImageVideoSampler,
|
||||
AspectRatioBatchSampler,
|
||||
RandomSampler, get_closest_ratio)
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_FUN_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox_inpaint import CogVideoX_FUN_Pipeline_Inpaint
|
||||
from cogvideox.pipeline.pipeline_cogvideox import CogVideoX_Fun_Pipeline
|
||||
from cogvideox.pipeline.pipeline_cogvideox_inpaint import CogVideoX_Fun_Pipeline_Inpaint
|
||||
from cogvideox.data.dataset_image import CC15M
|
||||
from cogvideox.data.dataset_image_video import (ImageVideoDataset,
|
||||
ImageVideoSampler,
|
||||
@@ -168,7 +168,7 @@ def log_validation(vae, text_encoder, tokenizer, transformer3d, network, args, a
|
||||
transformer3d_val.load_state_dict(accelerator.unwrap_model(transformer3d).state_dict())
|
||||
|
||||
if args.train_mode != "normal":
|
||||
pipeline = CogVideoX_FUN_Pipeline_Inpaint.from_pretrained(
|
||||
pipeline = CogVideoX_Fun_Pipeline_Inpaint.from_pretrained(
|
||||
args.pretrained_model_name_or_path,
|
||||
vae=accelerator.unwrap_model(vae).to(weight_dtype),
|
||||
text_encoder=accelerator.unwrap_model(text_encoder),
|
||||
@@ -177,7 +177,7 @@ def log_validation(vae, text_encoder, tokenizer, transformer3d, network, args, a
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
else:
|
||||
pipeline = CogVideoX_FUN_Pipeline.from_pretrained(
|
||||
pipeline = CogVideoX_Fun_Pipeline.from_pretrained(
|
||||
args.pretrained_model_name_or_path,
|
||||
vae=accelerator.unwrap_model(vae).to(weight_dtype),
|
||||
text_encoder=accelerator.unwrap_model(text_encoder),
|
||||
|
||||
Reference in New Issue
Block a user