Compare commits
9
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 bubbliiiing |
5bfdf9efe7 | ||
|
bubbliiiing
|
35f10236f2 | ||
|
bubbliiiing
|
17f67b059d | ||
|
bubbliiiing
|
6b993004fe | ||
|
bubbliiiing
|
90ccb43cab | ||
|
bubbliiiing
|
0834594d1b | ||
|
bubbliiiing
|
0f6337c1c5 | ||
|
bubbliiiing
|
dd661cf919 | ||
|
bubbliiiing
|
261e1d85d3 |
@@ -26,24 +26,6 @@ English | [简体中文](./README_zh-CN.md) | [日本語](./README_ja-JP.md)
|
||||
# I. Introduction
|
||||
VideoX-Fun is a video generation pipeline that can be used to generate AI images and videos, as well as to train baseline and Lora models for Diffusion Transformer. We support direct prediction from pre-trained baseline models to generate videos with different resolutions, durations, and FPS. Additionally, we also support users in training their own baseline and Lora models to perform specific style transformations.
|
||||
|
||||
What's New:
|
||||
- Added support for Wan 2.2 series models, Wan-VACE control model, Fantasy Talking digital human model, Qwen-Image, Flux image generation models, and more. [2025.10.16]
|
||||
- Update Wan2.1-Fun-V1.1: Support for 14B and 1.3B model Control + Reference Image models, support for camera control, and the Inpaint model has been retrained for improved performance. [2025.04.25]
|
||||
- Update Wan2.1-Fun-V1.0: Support I2V and Control models for 14B and 1.3B models, with support for start and end frame prediction. [2025.03.26]
|
||||
- Update CogVideoX-Fun-V1.5: Upload I2V model and related training/prediction code. [2024.12.16]
|
||||
- Reward Lora Support: Train Lora using reward backpropagation techniques to optimize generated videos, making them better aligned with human preferences. [More Information](scripts/README_TRAIN_REWARD.md). New version of the control model supports various control conditions such as Canny, Depth, Pose, MLSD, etc. [2024.11.21]
|
||||
- Diffusers Support: CogVideoX-Fun Control is now supported in diffusers. Thanks to [a-r-r-o-w](https://github.com/a-r-r-o-w) for contributing support in this [PR](https://github.com/huggingface/diffusers/pull/9671). Check out the [documentation](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cogvideox) for more details. [2024.10.16]
|
||||
- Update CogVideoX-Fun-V1.1: Retrain i2v model, add Noise to increase the motion amplitude of the video. Upload control model training code and Control model. [2024.09.29]
|
||||
- Update CogVideoX-Fun-V1.0: Initial code release! Now supports Windows and Linux. Supports video generation at arbitrary resolutions from 256x256x49 to 1024x1024x49 for 2B and 5B models. [2024.09.18]
|
||||
|
||||
Function:
|
||||
- [Data Preprocessing](#data-preprocess)
|
||||
- [Train DiT](#dit-train)
|
||||
- [Video Generation](#video-gen)
|
||||
|
||||
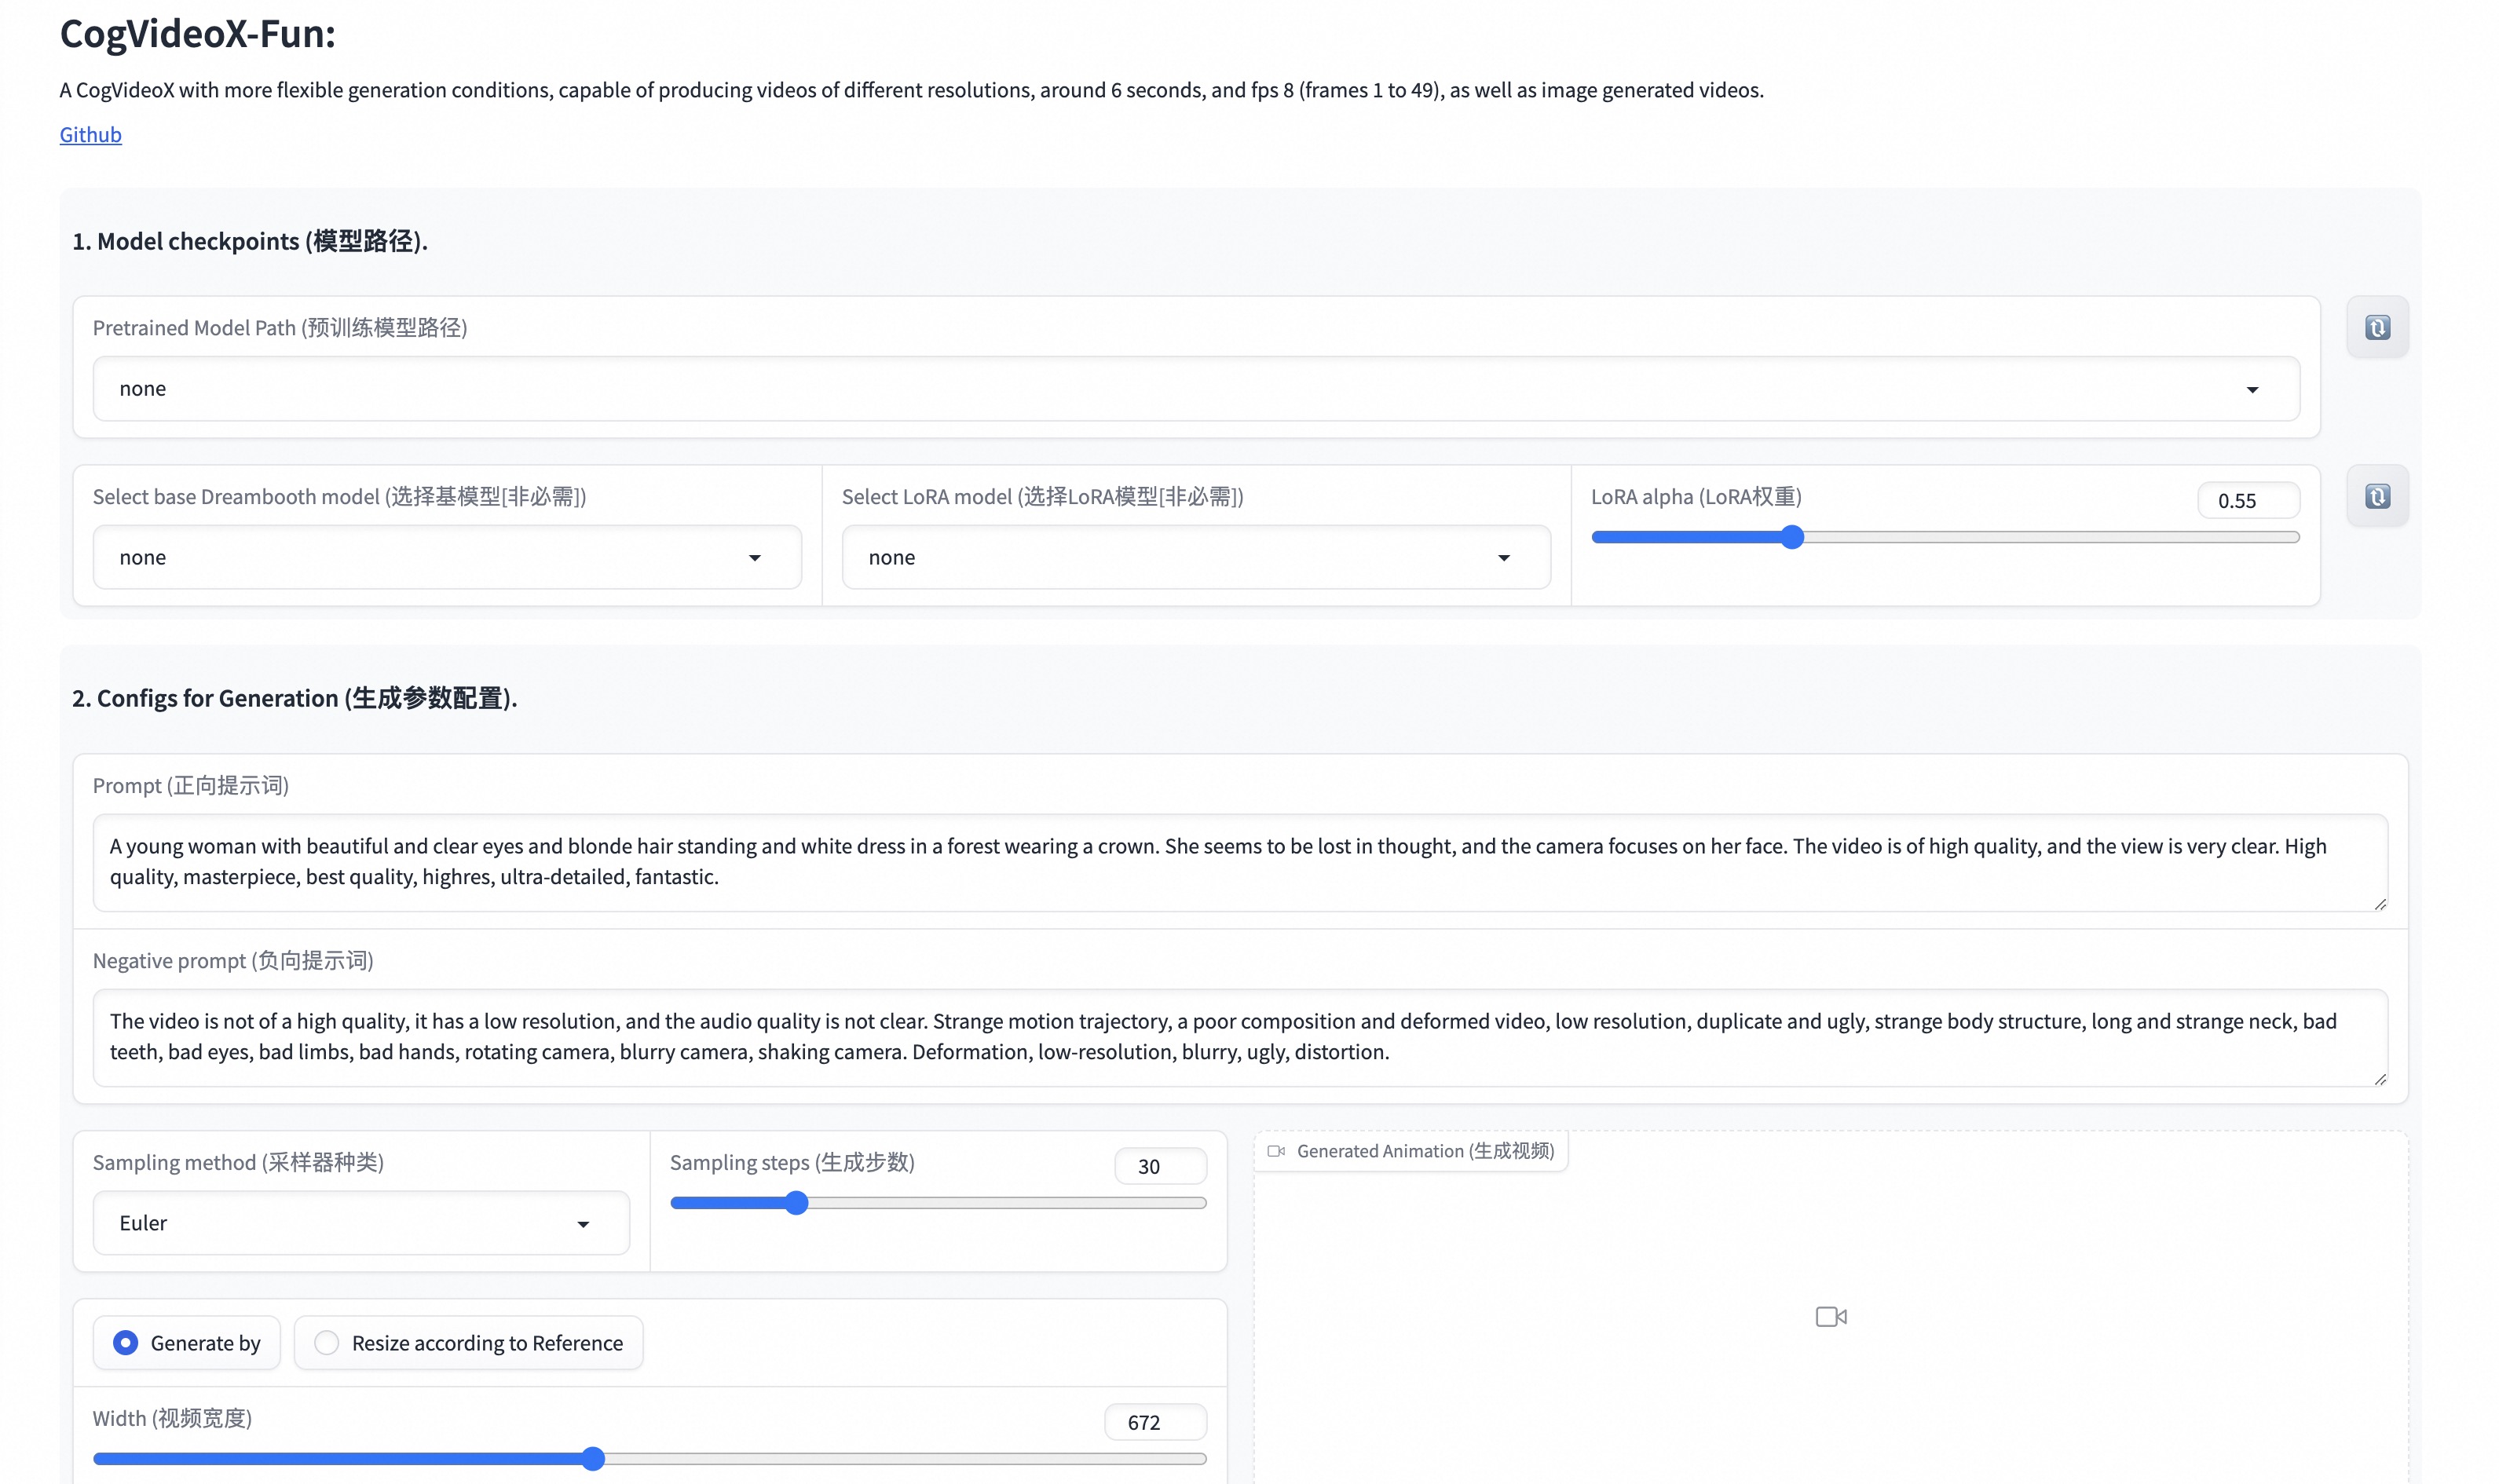
Our UI interface is as follows:
|
||||
|
||||
|
||||
# II. Quick Start and Usage
|
||||
|
||||
<a id="quick-start"></a>
|
||||
@@ -320,7 +302,7 @@ For parameter details, training documents for each model are unified under `scri
|
||||
| Wan2.2-Fun | [EN](scripts/wan2.2_fun/README_TRAIN.md) / [ZH](scripts/wan2.2_fun/README_TRAIN_zh-CN.md) | [EN](scripts/wan2.2_fun/README_TRAIN_LORA.md) / [ZH](scripts/wan2.2_fun/README_TRAIN_LORA_zh-CN.md) | [Control LoRA EN](scripts/wan2.2_fun/README_TRAIN_CONTROL_LORA.md) |
|
||||
| CogVideoX-Fun | [EN](scripts/cogvideox_fun/README_TRAIN.md) / [ZH](scripts/cogvideox_fun/README_TRAIN_zh-CN.md) | [EN](scripts/cogvideox_fun/README_TRAIN_LORA.md) / [ZH](scripts/cogvideox_fun/README_TRAIN_LORA_zh-CN.md) | [Control EN](scripts/cogvideox_fun/README_TRAIN_CONTROL.md)、[Reward LoRA](scripts/cogvideox_fun/README_TRAIN_REWARD.md) |
|
||||
| Qwen-Image | [EN](scripts/qwenimage/README_TRAIN.md) / [ZH](scripts/qwenimage/README_TRAIN_zh-CN.md) | [EN](scripts/qwenimage/README_TRAIN_LORA.md) / [ZH](scripts/qwenimage/README_TRAIN_LORA_zh-CN.md) | [Edit EN](scripts/qwenimage/README_TRAIN_EDIT.md) |
|
||||
| Qwen-Image-2.1 | [EN](scripts/qwenimage21/README_TRAIN.md) / [ZH](scripts/qwenimage21/README_TRAIN_zh-CN.md) | - | - |
|
||||
| Qwen-Image-2.1 | [EN](scripts/qwenimage21/README_TRAIN.md) / [ZH](scripts/qwenimage21/README_TRAIN_zh-CN.md) | - | [Control EN](scripts/qwenimage21_fun/README_TRAIN.md) / [ZH](scripts/qwenimage21_fun/README_TRAIN_zh-CN.md) |
|
||||
| Z-Image | [EN](scripts/z_image/README_TRAIN.md) / [ZH](scripts/z_image/README_TRAIN_zh-CN.md) | [EN](scripts/z_image/README_TRAIN_LORA.md) / [ZH](scripts/z_image/README_TRAIN_LORA_zh-CN.md) | [GRPO LoRA EN](scripts/z_image/README_TRAIN_GRPO_LORA.md) |
|
||||
|
||||
For other models, check the READMEs under `scripts/{model_name}/`.
|
||||
@@ -355,7 +337,7 @@ The table below summarizes currently supported model families and weights. Video
|
||||
| Phantom | Video | Incremental weights for multi-subject reference video generation; based on Wan2.1-T2V | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">1.3B version. Officially released as .pth; place in Personalized_Model and reference via transformer_path in predict file</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">14B version. Officially released as sharded safetensors</td></tr></table> |
|
||||
| Qwen-Image | Image | Official text-to-image and image-editing weights; supports baseline and LoRA training | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image">🤖</a></td><td valign="top" style="padding:2px 0;">文生图基础权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2512">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2512">🤖</a></td><td valign="top" style="padding:2px 0;">Updated text-to-image version</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit-2509</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit-2509">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑更新版本</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Layered</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Layered">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Layered">🤖</a></td><td valign="top" style="padding:2px 0;">Image layer-decomposition weights; splits an image into multiple editable RGBA layers</td></tr></table> |
|
||||
| Qwen-Image-2.1 | Image | Official next-generation text-to-image weights; single-stream block-causal transformer with prefix KV cache | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">Single-stream block-causal transformer; supports full-parameter training, prefix KV cache speeds up inference</td></tr></table> |
|
||||
| Qwen-Image ControlNet | Image | Image controlled generation; supports Canny, Depth, Pose, MLSD, and Scribble | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for Qwen-Image-2512, supporting multiple control conditions such as Canny, Depth, Pose, MLSD, Scribble, etc.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">Equivalent ControlNet provided by InstantX</td></tr></table> |
|
||||
| Qwen-Image ControlNet | Image | Image controlled generation; supports Canny, Depth, Pose, MLSD, and Scribble | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for Qwen-Image-2512, supporting multiple control conditions such as Canny, Depth, Pose, MLSD, Scribble, etc.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2.1-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2.1-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet-Union weights for Qwen-Image-2.1 trained by this project, supporting control conditions such as Canny, Depth, Pose, MLSD, and image inpainting</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">Equivalent ControlNet provided by InstantX</td></tr></table> |
|
||||
| Z-Image | Image | Official text-to-image weights | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image">🤖</a></td><td valign="top" style="padding:2px 0;">基础版</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image-Turbo">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo">🤖</a></td><td valign="top" style="padding:2px 0;">加速版</td></tr></table> |
|
||||
| Z-Image-Fun | Image | ControlNet and distillation LoRA trained by this project on Z-Image; supports Canny, Depth, Pose, MLSD, Scribble, and Gray | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for Z-Image. Compared to the first version, it adds to more layers and has been trained for a longer period. It supports multiple control conditions including Canny, Depth, Pose, MLSD, Scribble and Gray.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for Z-Image-Turbo, supporting multiple control conditions such as Canny, Depth, Pose, MLSD, etc.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for Z-Image-Turbo. Compared to the first version, it adds to more layers and has been trained for a longer period. It supports multiple control conditions including Canny, Depth, Pose, MLSD, and more.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Lora-Distill</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill">🤖</a></td><td valign="top" style="padding:2px 0;">This is a Distill LoRA for Z-Image that distills both steps and CFG. This model does not require CFG and uses 8 steps for inference.</td></tr></table> |
|
||||
| Flux | Image | Official FLUX.1/FLUX.2 weights and the ControlNet trained by this project | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.1-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.1-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev">🤖</a></td><td valign="top" style="padding:2px 0;">文生图与图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.2-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev">🤖</a></td><td valign="top" style="padding:2px 0;">第二代官方权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for FLUX.2-dev</td></tr></table> |
|
||||
@@ -375,16 +357,16 @@ The table below summarizes currently supported model families and weights. Video
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -392,21 +374,22 @@ The table below summarizes currently supported model families and weights. Video
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
|
||||
<details>
|
||||
<summary><b>Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control</b></summary>
|
||||
|
||||
Generic Control Video + Reference Image:
|
||||
|
||||
@@ -427,16 +410,16 @@ Generic Control Video + Reference Image:
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload="none"></image>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -447,13 +430,13 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -461,29 +444,32 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera</b></summary>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
@@ -499,13 +485,13 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
@@ -521,34 +507,37 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>CogVideoX-Fun-V1.1-5B</b></summary>
|
||||
|
||||
Resolution-1024
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -559,16 +548,16 @@ Resolution-768
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -578,32 +567,35 @@ Resolution-512
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B-Control
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>CogVideoX-Fun-V1.1-5B-Control</b></summary>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
@@ -619,17 +611,19 @@ Resolution-512
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
</details>
|
||||
|
||||
# V. References
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
|
||||
|
||||
+63
-69
@@ -26,24 +26,6 @@ Wan-Fun:
|
||||
# 一、紹介
|
||||
VideoX-Funはビデオ生成のパイプラインであり、AI画像やビデオの生成、Diffusion TransformerのベースラインモデルとLoraモデルのトレーニングに使用できます。我々は、すでに学習済みのベースラインモデルから直接予測を行い、異なる解像度、秒数、FPSのビデオを生成することをサポートしています。また、ユーザーが独自のベースラインモデルやLoraモデルをトレーニングし、特定のスタイル変換を行うこともサポートしています。
|
||||
|
||||
新機能:
|
||||
- Wan 2.2シリーズモデル、Wan-VACE制御モデル、Fantasy Talkingデジタルヒューマンモデル、Qwen-Image、Flux画像生成モデルなどのサポートを追加しました。[2025.10.16]
|
||||
- Wan2.1-Fun-V1.1バージョンを更新:14Bと1.3BモデルのControl+参照画像モデルをサポート、カメラ制御にも対応。さらに、Inpaintモデルを再訓練し、性能が向上しました。[2025.04.25]
|
||||
- Wan2.1-Fun-V1.0の更新:14Bおよび1.3BのI2V(画像からビデオ)モデルとControlモデルをサポートし、開始フレームと終了フレームの予測に対応。[2025.03.26]
|
||||
- CogVideoX-Fun-V1.5の更新:I2Vモデルと関連するトレーニング・予測コードをアップロード。[2024.12.16]
|
||||
- 報酬Loraのサポート:報酬逆伝播技術を使用してLoraをトレーニングし、生成された動画を最適化し、人間の好みによりよく一致させる。[詳細情報](scripts/README_TRAIN_REWARD.md)。新しいバージョンの制御モデルでは、Canny、Depth、Pose、MLSDなどの異なる制御条件に対応。[2024.11.21]
|
||||
- diffusersのサポート:CogVideoX-Fun Controlがdiffusersでサポートされるようになりました。[a-r-r-o-w](https://github.com/a-r-r-o-w)がこの[PR](https://github.com/huggingface/diffusers/pull/9671)でサポートを提供してくれたことに感謝します。詳細は[ドキュメント](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cogvideox)をご覧ください。[2024.10.16]
|
||||
- CogVideoX-Fun-V1.1の更新:i2vモデルを再トレーニングし、Noiseを追加して動画の動きの範囲を拡大。制御モデルのトレーニングコードとControlモデルをアップロード。[2024.09.29]
|
||||
- CogVideoX-Fun-V1.0の更新:コードを作成!WindowsとLinuxに対応しました。2Bおよび5Bモデルでの最大256x256x49から1024x1024x49までの任意の解像度の動画生成をサポート。[2024.09.18]
|
||||
|
||||
機能:
|
||||
- [データ前処理](#data-preprocess)
|
||||
- [DiTのトレーニング](#dit-train)
|
||||
- [ビデオ生成](#video-gen)
|
||||
|
||||
私たちのUIインターフェースは次のとおりです:
|
||||

|
||||
|
||||
# 二、クイックスタートと使用
|
||||
|
||||
<a id="quick-start"></a>
|
||||
@@ -320,7 +302,7 @@ sh scripts/{model_name}/train.sh
|
||||
| Wan2.2-Fun | [EN](scripts/wan2.2_fun/README_TRAIN.md) / [ZH](scripts/wan2.2_fun/README_TRAIN_zh-CN.md) | [EN](scripts/wan2.2_fun/README_TRAIN_LORA.md) / [ZH](scripts/wan2.2_fun/README_TRAIN_LORA_zh-CN.md) | [Control LoRA ZH](scripts/wan2.2_fun/README_TRAIN_CONTROL_LORA_zh-CN.md) |
|
||||
| CogVideoX-Fun | [EN](scripts/cogvideox_fun/README_TRAIN.md) / [ZH](scripts/cogvideox_fun/README_TRAIN_zh-CN.md) | [EN](scripts/cogvideox_fun/README_TRAIN_LORA.md) / [ZH](scripts/cogvideox_fun/README_TRAIN_LORA_zh-CN.md) | [Control ZH](scripts/cogvideox_fun/README_TRAIN_CONTROL_zh-CN.md)、[Reward LoRA](scripts/cogvideox_fun/README_TRAIN_REWARD.md) |
|
||||
| Qwen-Image | [EN](scripts/qwenimage/README_TRAIN.md) / [ZH](scripts/qwenimage/README_TRAIN_zh-CN.md) | [EN](scripts/qwenimage/README_TRAIN_LORA.md) / [ZH](scripts/qwenimage/README_TRAIN_LORA_zh-CN.md) | [Edit ZH](scripts/qwenimage/README_TRAIN_EDIT_zh-CN.md) |
|
||||
| Qwen-Image-2.1 | [EN](scripts/qwenimage21/README_TRAIN.md) / [ZH](scripts/qwenimage21/README_TRAIN_zh-CN.md) | - | - |
|
||||
| Qwen-Image-2.1 | [EN](scripts/qwenimage21/README_TRAIN.md) / [ZH](scripts/qwenimage21/README_TRAIN_zh-CN.md) | - | [Control EN](scripts/qwenimage21_fun/README_TRAIN.md) / [ZH](scripts/qwenimage21_fun/README_TRAIN_zh-CN.md) |
|
||||
| Z-Image | [EN](scripts/z_image/README_TRAIN.md) / [ZH](scripts/z_image/README_TRAIN_zh-CN.md) | [EN](scripts/z_image/README_TRAIN_LORA.md) / [ZH](scripts/z_image/README_TRAIN_LORA_zh-CN.md) | [GRPO LoRA](scripts/z_image/README_TRAIN_GRPO_LORA.md) |
|
||||
|
||||
その他のモデルも同様に、対応する`scripts/{model_name}/`下のREADMEを参照してください。
|
||||
@@ -355,7 +337,7 @@ sh scripts/{model_name}/train.sh
|
||||
| Phantom | ビデオ | 複数主体参照による動画生成の増分重み。Wan2.1-T2Vベース | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">1.3B版。公式は.pth形式で公開。Personalized_Modelに配置しpredictファイルのtransformer_pathで指定</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">14B版。公式は分割safetensors形式で公開</td></tr></table> |
|
||||
| Qwen-Image | 画像 | 公式テキストから画像生成・画像編集重み。基線とLoRA訓練をサポート | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image">🤖</a></td><td valign="top" style="padding:2px 0;">文生图基础权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2512">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2512">🤖</a></td><td valign="top" style="padding:2px 0;">テキストから画像生成の更新版</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit-2509</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit-2509">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑更新版本</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Layered</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Layered">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Layered">🤖</a></td><td valign="top" style="padding:2px 0;">画像レイヤー分解重み。画像を複数の編集可能なRGBAレイヤーに分解可能</td></tr></table> |
|
||||
| Qwen-Image-2.1 | 画像 | 公式次世代テキストから画像生成重み。シングルストリームblock-causal構造、プレフィックスKV cacheに対応 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">シングルストリームblock-causal構造。全パラメータ訓練をサポート、プレフィックスKV cacheで推論を高速化</td></tr></table> |
|
||||
| Qwen-Image ControlNet | 画像 | 画像制御生成。Canny、Depth、Pose、MLSD、Scribbleをサポート | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">Qwen-Image-2512のControlNet重み。Canny、Depth、Pose、MLSD、Scribbleなど、複数の制御条件をサポートします。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">InstantX提供の同種ControlNet</td></tr></table> |
|
||||
| Qwen-Image ControlNet | 画像 | 画像制御生成。Canny、Depth、Pose、MLSD、Scribbleをサポート | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">Qwen-Image-2512のControlNet重み。Canny、Depth、Pose、MLSD、Scribbleなど、複数の制御条件をサポートします。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2.1-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2.1-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">本プロジェクトがQwen-Image 2.1向けに訓練したControlNet-Union。Canny、Depth、Pose、MLSDなどの制御条件と画像補完(inpaint)をサポートします。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">InstantX提供の同種ControlNet</td></tr></table> |
|
||||
| Z-Image | 画像 | 公式テキストから画像生成重み | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image">🤖</a></td><td valign="top" style="padding:2px 0;">基础版</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image-Turbo">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo">🤖</a></td><td valign="top" style="padding:2px 0;">加速版</td></tr></table> |
|
||||
| Z-Image-Fun | 画像 | 本プロジェクトがZ-Imageで訓練したControlNetと蒸留LoRA。Canny、Depth、Pose、MLSD、Scribble、Grayをサポート | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">Z-ImageのControlNet重み、Canny、Depth、Pose、MLSD、ScribbleおよびGrayなど複数の制御条件に対応。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">Z-Image-Turbo用のControlNet重み。Canny、Depth、Pose、MLSDなど複数の制御条件をサポート。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">Z-Image-TurboのControlNet重み。第1版と比較して、より多くの層に追加され、より長時間トレーニングされています。Canny、Depth、Pose、MLSDなど、複数の制御条件をサポートしています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Lora-Distill</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill">🤖</a></td><td valign="top" style="padding:2px 0;">これはZ-Image用の蒸留LoRAで、ステップ数とCFGの両方を蒸留します。このモデルはCFGを必要とせず、推論には8ステップを使用します。</td></tr></table> |
|
||||
| Flux | 画像 | 公式FLUX.1/FLUX.2重みと本プロジェクトが訓練したControlNet | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.1-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.1-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev">🤖</a></td><td valign="top" style="padding:2px 0;">文生图与图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.2-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev">🤖</a></td><td valign="top" style="padding:2px 0;">第二代官方权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">FLUX.2-dev用ControlNet重み</td></tr></table> |
|
||||
@@ -375,16 +357,16 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -392,21 +374,22 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
|
||||
<details>
|
||||
<summary><b>Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control</b></summary>
|
||||
|
||||
汎用制御動画 + 参照画像:
|
||||
|
||||
@@ -427,16 +410,16 @@ sh scripts/{model_name}/train.sh
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload="none"></image>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -447,13 +430,13 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -461,29 +444,32 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera</b></summary>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
@@ -499,13 +485,13 @@ sh scripts/{model_name}/train.sh
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
@@ -521,34 +507,37 @@ sh scripts/{model_name}/train.sh
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>CogVideoX-Fun-V1.1-5B</b></summary>
|
||||
|
||||
解像度-1024
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -559,16 +548,16 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -578,32 +567,35 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B-Control
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>CogVideoX-Fun-V1.1-5B-Control</b></summary>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
@@ -619,17 +611,19 @@ sh scripts/{model_name}/train.sh
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
</details>
|
||||
|
||||
# 五、参考文献
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
|
||||
|
||||
+19
-19
@@ -299,7 +299,7 @@ sh scripts/{model_name}/train.sh
|
||||
| Wan2.2-Fun | [中文](scripts/wan2.2_fun/README_TRAIN_zh-CN.md) / [EN](scripts/wan2.2_fun/README_TRAIN.md) | [中文](scripts/wan2.2_fun/README_TRAIN_LORA_zh-CN.md) / [EN](scripts/wan2.2_fun/README_TRAIN_LORA.md) | [Control LoRA 中文](scripts/wan2.2_fun/README_TRAIN_CONTROL_LORA_zh-CN.md) |
|
||||
| CogVideoX-Fun | [中文](scripts/cogvideox_fun/README_TRAIN_zh-CN.md) / [EN](scripts/cogvideox_fun/README_TRAIN.md) | [中文](scripts/cogvideox_fun/README_TRAIN_LORA_zh-CN.md) / [EN](scripts/cogvideox_fun/README_TRAIN_LORA.md) | [Control 中文](scripts/cogvideox_fun/README_TRAIN_CONTROL_zh-CN.md)、[Reward LoRA](scripts/cogvideox_fun/README_TRAIN_REWARD.md) |
|
||||
| Qwen-Image | [中文](scripts/qwenimage/README_TRAIN_zh-CN.md) / [EN](scripts/qwenimage/README_TRAIN.md) | [中文](scripts/qwenimage/README_TRAIN_LORA_zh-CN.md) / [EN](scripts/qwenimage/README_TRAIN_LORA.md) | [Edit 中文](scripts/qwenimage/README_TRAIN_EDIT_zh-CN.md) |
|
||||
| Qwen-Image-2.1 | [中文](scripts/qwenimage21/README_TRAIN_zh-CN.md) / [EN](scripts/qwenimage21/README_TRAIN.md) | - | - |
|
||||
| Qwen-Image-2.1 | [中文](scripts/qwenimage21/README_TRAIN_zh-CN.md) / [EN](scripts/qwenimage21/README_TRAIN.md) | - | [Control 中文](scripts/qwenimage21_fun/README_TRAIN_zh-CN.md) / [EN](scripts/qwenimage21_fun/README_TRAIN.md) |
|
||||
| Z-Image | [中文](scripts/z_image/README_TRAIN_zh-CN.md) / [EN](scripts/z_image/README_TRAIN.md) | [中文](scripts/z_image/README_TRAIN_LORA_zh-CN.md) / [EN](scripts/z_image/README_TRAIN_LORA.md) | [GRPO LoRA 中文](scripts/z_image/README_TRAIN_GRPO_LORA_zh-CN.md) |
|
||||
|
||||
其余模型(如HunyuanVideo、MiniMax-H3、Flux2-Fun、InfiniteTalk、LingBot等)同理,直接查看对应`scripts/{model_name}/`下的README即可。
|
||||
@@ -334,7 +334,7 @@ sh scripts/{model_name}/train.sh
|
||||
| Phantom | 视频 | 多主体参考生视频的增量权重,基于Wan2.1-T2V | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">1.3B版,官方以.pth发布,放入Personalized_Model后按预测脚本的transformer_path引用</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">14B版,官方以分片safetensors发布</td></tr></table> |
|
||||
| Qwen-Image | 图片 | 官方文生图与图像编辑权重,支持基线与LoRA训练 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image">🤖</a></td><td valign="top" style="padding:2px 0;">文生图基础权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2512">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2512">🤖</a></td><td valign="top" style="padding:2px 0;">文生图更新版本</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit-2509</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit-2509">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑更新版本</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Layered</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Layered">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Layered">🤖</a></td><td valign="top" style="padding:2px 0;">图像图层分解权重,可将图像拆分为多个可编辑的RGBA图层</td></tr></table> |
|
||||
| Qwen-Image-2.1 | 图片 | 官方新一代文生图权重,单流block-causal结构,支持前缀KV cache | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">单流block-causal结构,支持全参数训练;前缀KV cache可加速推理</td></tr></table> |
|
||||
| Qwen-Image ControlNet | 图片 | 图片控制生成,支持Canny、Depth、Pose、MLSD、Scribble | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">本项目训练的ControlNet</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">InstantX提供的同类型ControlNet</td></tr></table> |
|
||||
| Qwen-Image ControlNet | 图片 | 图片控制生成,支持Canny、Depth、Pose、MLSD、Scribble | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">本项目训练的ControlNet</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2.1-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2.1-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">本项目为 Qwen-Image-2.1 训练的 ControlNet-Union,支持 Canny、Depth、Pose、MLSD 等控制条件与图像修复(inpaint)</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">InstantX提供的同类型ControlNet</td></tr></table> |
|
||||
| Z-Image | 图片 | 官方文生图权重 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image">🤖</a></td><td valign="top" style="padding:2px 0;">基础版</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image-Turbo">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo">🤖</a></td><td valign="top" style="padding:2px 0;">加速版</td></tr></table> |
|
||||
| Z-Image-Fun | 图片 | 本项目在Z-Image上训练的ControlNet与蒸馏LoRA,控制条件支持Canny、Depth、Pose、MLSD、Scribble、Gray | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">基于基础版的ControlNet,2.1版层数更多、训练更充分</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">基于Turbo的ControlNet</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">基于Turbo的2.1版ControlNet,仓库含多精度文件</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Lora-Distill</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill">🤖</a></td><td valign="top" style="padding:2px 0;">同时蒸馏步数与CFG,推理仅需8步</td></tr></table> |
|
||||
| Flux | 图片 | 官方FLUX.1/FLUX.2权重与本项目训练的ControlNet | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.1-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.1-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev">🤖</a></td><td valign="top" style="padding:2px 0;">文生图与图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.2-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev">🤖</a></td><td valign="top" style="padding:2px 0;">第二代官方权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">本项目为FLUX.2-dev训练的ControlNet,支持Canny、Depth、Pose、MLSD等</td></tr></table> |
|
||||
@@ -354,16 +354,16 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -388,16 +388,16 @@ sh scripts/{model_name}/train.sh
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload="none"></image>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -408,13 +408,13 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -422,24 +422,24 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload loop></video>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload="none"></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
@@ -317,6 +317,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -256,6 +256,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -251,6 +251,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -236,6 +236,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -201,6 +201,7 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -321,6 +321,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -248,6 +248,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -161,7 +161,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.text_model.encoder.layers)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -215,6 +215,7 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -156,7 +156,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -209,6 +209,7 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -172,7 +172,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers, ignored_modules=[text_encoder.language_model.embed_tokens], transformer_layer_cls_to_wrap=["MistralDecoderLayer", "PixtralTransformer"])
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -249,6 +249,7 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -258,6 +258,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -243,6 +243,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -305,6 +305,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -217,6 +217,7 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -241,6 +241,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -242,6 +242,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -360,6 +360,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -235,6 +235,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -279,6 +279,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -227,6 +227,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -218,7 +218,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype,
|
||||
module_to_wrapper=text_encoder.language_model.layers)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -292,6 +292,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
sr = getattr(pipeline.vocoder.config, "output_sampling_rate", audio_sample_rate)
|
||||
|
||||
@@ -214,7 +214,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype,
|
||||
module_to_wrapper=text_encoder.language_model.layers)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -287,6 +287,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
sr = getattr(pipeline.vocoder.config, "output_sampling_rate", audio_sample_rate)
|
||||
|
||||
@@ -202,7 +202,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype,
|
||||
module_to_wrapper=text_encoder.language_model.layers)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -268,6 +268,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
sr = getattr(pipeline.vocoder.config, "output_sampling_rate", audio_sample_rate)
|
||||
|
||||
@@ -206,7 +206,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype,
|
||||
module_to_wrapper=text_encoder.language_model.layers)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -313,6 +313,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
sr = getattr(pipeline.vocoder.config, "output_sampling_rate", audio_sample_rate)
|
||||
|
||||
@@ -198,7 +198,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype,
|
||||
module_to_wrapper=text_encoder.language_model.layers)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -263,6 +263,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
sr = getattr(pipeline.vocoder.config, "output_sampling_rate", audio_sample_rate)
|
||||
|
||||
@@ -367,6 +367,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
sr = getattr(pipeline.audio_vae.config, "output_sampling_rate", audio_sample_rate)
|
||||
|
||||
@@ -296,6 +296,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -184,7 +184,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -254,6 +254,7 @@ def save_results():
|
||||
prefix = str(index).zfill(8)
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
_image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -172,7 +172,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -237,6 +237,7 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -183,7 +183,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -253,6 +253,7 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -158,7 +158,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.model.language_model.layers)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -214,6 +214,7 @@ for prompt in prompts:
|
||||
image_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(image_path)
|
||||
print(f"Saved image to: {image_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -0,0 +1,261 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import torch
|
||||
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLQwenImage21,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor,
|
||||
QwenImage21ControlTransformer2DModel)
|
||||
from videox_fun.pipeline import QwenImage21ControlPipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import get_image_latent
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "model_group_offload"
|
||||
# Multi GPUs config
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = False
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with the fsdp_dit and sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# Config path (control_layers / control_in_dim live here and must match the trained adapter)
|
||||
config_path = "config/qwenimage21/qwenimage21_control.yaml"
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
|
||||
# Choose the sampler. Qwen-Image 2.1 is a flow-matching model sampled with the Euler discrete scheduler.
|
||||
sampler_name = "Flow"
|
||||
|
||||
# Load pretrained model if need
|
||||
transformer_path = "models/Personalized_Model/Qwen-Image-2.1-Fun-Controlnet-Union.safetensors"
|
||||
vae_path = None
|
||||
lora_path = None
|
||||
|
||||
# Other params
|
||||
sample_size = [1728, 992]
|
||||
# Cache the text and condition-image keys/values after the first denoising step. Valid because the
|
||||
# transformer modulates those tokens from t = 0, making their activations step-independent.
|
||||
use_kv_cache = True
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_image = "asset/pose.jpg"
|
||||
inpaint_image = "asset/8.png"
|
||||
mask_image = "asset/mask.png"
|
||||
# Strength of the control/union branch. 1.0 is the value the adapter is trained to consume.
|
||||
control_context_scale = 1.0
|
||||
|
||||
# Describe what should appear inside the masked (white) region.
|
||||
prompt = "A young woman with long straight black hair in an elegant three-quarter pose, wearing a white off-shoulder top with delicate lace trim, soft studio lighting against a dark blue-grey gradient background, high-fashion portrait photography, shallow depth of field."
|
||||
negative_prompt = "低分辨率,低画质,肢体畸形,手指畸形,画面过饱和,蜡像感,人脸无细节,过度光滑,画面具有AI感。构图混乱。文字模糊,扭曲。"
|
||||
guidance_scale = 1.0
|
||||
seed = 43
|
||||
num_inference_steps = 40
|
||||
lora_weight = 1.0
|
||||
save_path = "samples/qwenimage21-inpaint-images"
|
||||
|
||||
assert ring_degree == 1, (
|
||||
"Qwen-Image 2.1 only supports Ulysses (head-parallel) sequence parallelism; ring_degree must be 1, "
|
||||
"because ring attention cannot express the block-causal mask or the prefix KV cache."
|
||||
)
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
config = OmegaConf.load(config_path)
|
||||
|
||||
# Transformer
|
||||
transformer = QwenImage21ControlTransformer2DModel.from_pretrained(
|
||||
model_name,
|
||||
subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Vae
|
||||
vae = AutoencoderKLQwenImage21.from_pretrained(
|
||||
model_name,
|
||||
subfolder="vae"
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get processor and text_encoder. Qwen-Image 2.1 encodes the prompt (and any condition images) with a
|
||||
# Qwen3-VL model, so a processor replaces the plain tokenizer used by the earlier Qwen-Image families.
|
||||
processor = Qwen3VLProcessor.from_pretrained(
|
||||
model_name, subfolder="processor"
|
||||
)
|
||||
text_encoder = Qwen3VLForConditionalGeneration.from_pretrained(
|
||||
model_name, subfolder="text_encoder", torch_dtype=weight_dtype
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
}[sampler_name]
|
||||
scheduler = Chosen_Scheduler.from_pretrained(
|
||||
model_name,
|
||||
subfolder="scheduler"
|
||||
)
|
||||
|
||||
pipeline = QwenImage21ControlPipeline(
|
||||
vae=vae,
|
||||
text_encoder=text_encoder,
|
||||
processor=processor,
|
||||
transformer=transformer,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=list(transformer.transformer_blocks) + list(transformer.control_blocks))
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=pipeline.text_encoder.model.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.transformer_blocks)):
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "time_text_embed", "modulation"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "time_text_embed", "modulation"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
# Load the conditions through get_image_latent -- the same single-frame tensors that
|
||||
# scripts/qwenimage21_fun/train_control.py validation builds -- so the resize / normalization the model was
|
||||
# trained with is reproduced here; the pipeline only preprocesses them further and assembles
|
||||
# control_context = [control_latents(64) | mask(1) | masked-image latents(64)] = 129 ch.
|
||||
if inpaint_image is not None:
|
||||
inpaint_image_input = get_image_latent(inpaint_image, sample_size=sample_size)[:, :, 0]
|
||||
else:
|
||||
inpaint_image_input = torch.zeros([1, 3, sample_size[0], sample_size[1]])
|
||||
|
||||
# In the mask, WHITE (>= 0.5) marks the region to REGENERATE and BLACK the region to KEEP -- the convention used
|
||||
# during training. get_image_latent opens it through convert("RGB"), which also resolves palette (mode "P") PNGs
|
||||
# by their rendered grey value instead of the raw palette index (asset/mask.png: 54.6% vs 0.29% regenerate area).
|
||||
if mask_image is not None:
|
||||
mask_image_input = get_image_latent(mask_image, sample_size=sample_size)[:, :1, 0]
|
||||
else:
|
||||
mask_image_input = torch.ones([1, 1, sample_size[0], sample_size[1]]) * 255
|
||||
|
||||
if control_image is not None:
|
||||
control_image_input = get_image_latent(control_image, sample_size=sample_size)[:, :, 0]
|
||||
else:
|
||||
control_image_input = None
|
||||
|
||||
with torch.no_grad():
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
negative_prompt = negative_prompt,
|
||||
height = sample_size[0],
|
||||
width = sample_size[1],
|
||||
generator = generator,
|
||||
true_cfg_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
image = inpaint_image_input,
|
||||
mask_image = mask_image_input,
|
||||
control_image = control_image_input,
|
||||
control_context_scale = control_context_scale,
|
||||
use_kv_cache = use_kv_cache,
|
||||
).images
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
# 2.1's VAE decodes to RGBA; JPEG cannot store an alpha channel, so every preview is saved as PNG.
|
||||
image_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(image_path)
|
||||
print(f"Saved image to: {image_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
else:
|
||||
save_results()
|
||||
@@ -0,0 +1,242 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import torch
|
||||
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLQwenImage21,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor,
|
||||
QwenImage21ControlTransformer2DModel)
|
||||
from videox_fun.pipeline import QwenImage21ControlPipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import get_image_latent
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "model_group_offload"
|
||||
# Multi GPUs config
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = False
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with the fsdp_dit and sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# Config path (control_layers / control_in_dim live here and must match the trained adapter)
|
||||
config_path = "config/qwenimage21/qwenimage21_control.yaml"
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
|
||||
# Choose the sampler. Qwen-Image 2.1 is a flow-matching model sampled with the Euler discrete scheduler.
|
||||
sampler_name = "Flow"
|
||||
|
||||
# Load pretrained model if need
|
||||
transformer_path = "models/Personalized_Model/Qwen-Image-2.1-Fun-Controlnet-Union.safetensors"
|
||||
vae_path = None
|
||||
lora_path = None
|
||||
|
||||
# Other params
|
||||
sample_size = [1728, 992]
|
||||
# Cache the text and condition-image keys/values after the first denoising step. Valid because the
|
||||
# transformer modulates those tokens from t = 0, making their activations step-independent.
|
||||
use_kv_cache = True
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_image = "asset/pose.jpg"
|
||||
control_context_scale = 1.0
|
||||
|
||||
# Please use as detailed a prompt as possible to describe the object that needs to be generated.
|
||||
prompt = "画面中央是一位年轻女孩,她拥有一头令人印象深刻的亮紫色长发,发丝在海风中轻盈飘扬,营造出动感而唯美的效果。她的长发两侧各扎着黑色蝴蝶结发饰,增添了几分可爱与俏皮感。女孩身穿一袭纯白色无袖连衣裙,裙摆轻盈飘逸,与她清新的气质完美契合。她的妆容精致自然,淡粉色的唇妆和温柔的眼神流露出恬静优雅的气质。她单手叉腰,姿态自信从容,目光直视镜头,展现出既甜美又不失个性的魅力。背景是一片开阔的海景,湛蓝的海水在阳光照射下波光粼粼,闪烁着钻石般的光芒。天空呈现出清澈的蔚蓝色,点缀着几朵洁白的云朵,营造出晴朗明媚的夏日氛围。画面前景右下角可见粉紫色的小花丛和绿色植物,为整体构图增添了自然生机和色彩层次。整张照片色调明亮清新,紫色头发与白色裙装、蓝色海天形成鲜明而和谐的色彩对比。"
|
||||
negative_prompt = " "
|
||||
guidance_scale = 1.0
|
||||
seed = 43
|
||||
num_inference_steps = 40
|
||||
lora_weight = 0.55
|
||||
save_path = "samples/qwenimage21-control-images"
|
||||
|
||||
assert ring_degree == 1, (
|
||||
"Qwen-Image 2.1 only supports Ulysses (head-parallel) sequence parallelism; ring_degree must be 1, "
|
||||
"because ring attention cannot express the block-causal mask or the prefix KV cache."
|
||||
)
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
config = OmegaConf.load(config_path)
|
||||
|
||||
# Transformer
|
||||
transformer = QwenImage21ControlTransformer2DModel.from_pretrained(
|
||||
model_name,
|
||||
subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Vae
|
||||
vae = AutoencoderKLQwenImage21.from_pretrained(
|
||||
model_name,
|
||||
subfolder="vae"
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get processor and text_encoder. Qwen-Image 2.1 encodes the prompt (and any condition images) with a
|
||||
# Qwen3-VL model, so a processor replaces the plain tokenizer used by the earlier Qwen-Image families.
|
||||
processor = Qwen3VLProcessor.from_pretrained(
|
||||
model_name, subfolder="processor"
|
||||
)
|
||||
text_encoder = Qwen3VLForConditionalGeneration.from_pretrained(
|
||||
model_name, subfolder="text_encoder", torch_dtype=weight_dtype
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
}[sampler_name]
|
||||
scheduler = Chosen_Scheduler.from_pretrained(
|
||||
model_name,
|
||||
subfolder="scheduler"
|
||||
)
|
||||
|
||||
pipeline = QwenImage21ControlPipeline(
|
||||
vae=vae,
|
||||
text_encoder=text_encoder,
|
||||
processor=processor,
|
||||
transformer=transformer,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=list(transformer.transformer_blocks) + list(transformer.control_blocks))
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=pipeline.text_encoder.model.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.transformer_blocks)):
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "time_text_embed", "modulation"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "time_text_embed", "modulation"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
# Load the control image through get_image_latent -- the same single-frame (1, 3, h, w) tensor that
|
||||
# scripts/qwenimage21_fun/train_control.py validation builds, so the resize / normalization the model was trained
|
||||
# with is reproduced here instead of relying on the pipeline's own PIL preprocessing.
|
||||
if control_image is not None:
|
||||
control_image_input = get_image_latent(control_image, sample_size=sample_size)[:, :, 0]
|
||||
else:
|
||||
control_image_input = None
|
||||
|
||||
with torch.no_grad():
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
negative_prompt = negative_prompt,
|
||||
height = sample_size[0],
|
||||
width = sample_size[1],
|
||||
generator = generator,
|
||||
true_cfg_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
control_image = control_image_input,
|
||||
control_context_scale = control_context_scale,
|
||||
use_kv_cache = use_kv_cache,
|
||||
).images
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
# 2.1's VAE decodes to RGBA; JPEG cannot store an alpha channel, so every preview is saved as PNG.
|
||||
image_path = os.path.join(save_path, prefix + f"-{control_context_scale}.png")
|
||||
image = sample[0]
|
||||
image.save(image_path)
|
||||
print(f"Saved image to: {image_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
else:
|
||||
save_results()
|
||||
@@ -185,7 +185,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -268,6 +268,7 @@ def save_results():
|
||||
image_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(image_path)
|
||||
print(f"Saved image to: {image_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -202,7 +202,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -272,6 +272,7 @@ def save_results():
|
||||
image_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(image_path)
|
||||
print(f"Saved image to: {image_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -314,6 +314,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -256,6 +256,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -298,6 +298,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -323,6 +323,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -279,6 +279,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -304,6 +304,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -316,6 +316,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -363,6 +363,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -78,7 +78,7 @@ shift = 5
|
||||
# Any Wan2.1 / CausVid / Self-Forcing checkpoint loads as-is: the Flex-Forcing
|
||||
# backbone inherits every parameter name and only the new `flex_kproj.*` tensors
|
||||
# are reported missing (they are identity-initialised, so step 0 is unchanged).
|
||||
transformer_path = "output_dir_wan2.1_flex_forcing_distill/checkpoint-1000/diffusion_pytorch_model.safetensors"
|
||||
transformer_path = "output_dir_wan2.1_flex_forcing_distill/checkpoint-3000/diffusion_pytorch_model.safetensors"
|
||||
vae_path = None
|
||||
lora_path = None
|
||||
|
||||
@@ -99,6 +99,12 @@ fps = 16
|
||||
# so there is no second number to keep in sync. Levels only ever
|
||||
# *add* boundaries, so a KV cache written at a coarse level stays
|
||||
# valid at a finer one.
|
||||
# "full_then_blocks" -> first denoising step runs the whole clip as one
|
||||
# bidirectional ("full") chunk, every later step is the block-major
|
||||
# Self-Forcing schedule over `num_frame_per_block`. A fixed 2-level
|
||||
# ladder - coarser than the binary pyramid, no `min_num_frame_per_
|
||||
# block` involvement; needs `num_inference_steps >= 2` for the
|
||||
# block-major steps to actually run.
|
||||
# An int instead pins a truncated pyramid of exactly that many levels; for 21
|
||||
# latent frames (= 81 pixel frames) that ladder is
|
||||
# 2 -> [[21], [11, 10]] 3 -> [[21], [11, 10], [6, 5, 5, 5]]
|
||||
@@ -109,12 +115,6 @@ denoise_mode = "pyramid"
|
||||
# 3 -> leaves stay 3-frame blocks (classic Self-Forcing granularity); the
|
||||
# ladder then converges early and later steps reuse its finest level.
|
||||
min_num_frame_per_block = 1
|
||||
# Advanced: the 3.1 partition itself can also be pinned on the pipeline call
|
||||
# (`chunk_spec = "18-3" / "ar" / "uniform:3"`); the pyramid above does not need
|
||||
# it, since it derives every level from the whole-clip level 0.
|
||||
# 3.3's K-Projection (the noise-level aligned Pi_{t<-0} of the cached clean keys)
|
||||
# is deliberately not configurable here: the model builds `diag_rank1` and applies
|
||||
# it on every call, so there is nothing left to set.
|
||||
# --- Causal backbone (inherited from Self-Forcing) -------------------------
|
||||
# `num_frame_per_block` only takes effect once the pyramid is off; the rollout
|
||||
# derives the block size from the partition itself otherwise. `context_noise`
|
||||
@@ -331,6 +331,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -345,6 +345,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(image_path)
|
||||
print(f"Saved image to: {image_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + "-edited.mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -299,6 +299,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -318,6 +318,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -329,6 +329,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -330,6 +330,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -262,6 +262,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -325,6 +325,7 @@ for prompt in prompts:
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -309,6 +309,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -308,6 +308,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -380,6 +380,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -351,6 +351,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -373,6 +373,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -341,6 +341,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -355,6 +355,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -372,6 +372,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -354,6 +354,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -403,6 +403,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -417,6 +417,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -356,6 +356,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -350,6 +350,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -394,6 +394,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -409,6 +409,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -350,6 +350,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -381,6 +381,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -387,6 +387,7 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -154,7 +154,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=list(text_encoder.model.layers))
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -207,6 +207,7 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -170,7 +170,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=list(text_encoder.model.layers))
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -241,6 +241,7 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -171,7 +171,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=list(text_encoder.model.layers))
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -242,6 +242,7 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -178,7 +178,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=list(text_encoder.model.layers))
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -249,6 +249,7 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -170,7 +170,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=list(text_encoder.model.layers))
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -241,6 +241,7 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -171,7 +171,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=list(text_encoder.model.layers))
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -242,6 +242,7 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user