Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 liubo0902 |
efcc128fd4 | ||
|
宣源
|
ed0a9dd9b0 | ||
|
宣源
|
13c0091109 | ||
|
宣源
|
a49ebb962c |
@@ -1,28 +0,0 @@
|
||||
name: Publish to Comfy registry
|
||||
on:
|
||||
workflow_dispatch:
|
||||
push:
|
||||
branches:
|
||||
- main
|
||||
- master
|
||||
paths:
|
||||
- "pyproject.toml"
|
||||
|
||||
permissions:
|
||||
issues: write
|
||||
|
||||
jobs:
|
||||
publish-node:
|
||||
name: Publish Custom Node to registry
|
||||
runs-on: ubuntu-latest
|
||||
if: ${{ github.repository_owner == 'aigc-apps' }}
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
submodules: true
|
||||
- name: Publish Custom Node
|
||||
uses: Comfy-Org/publish-node-action@v1
|
||||
with:
|
||||
## Add your own personal access token to your Github Repository secrets and reference it here.
|
||||
personal_access_token: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
@@ -6,12 +6,9 @@ taming*
|
||||
samples*
|
||||
datasets*
|
||||
asset*
|
||||
_*
|
||||
logs*
|
||||
__pycache__/
|
||||
*.py[cod]
|
||||
*$py.class
|
||||
scripts_demo*
|
||||
|
||||
# C extensions
|
||||
*.so
|
||||
|
||||
@@ -1,52 +0,0 @@
|
||||
FROM nvidia/cuda:12.1.0-cudnn8-devel-ubuntu22.04
|
||||
ENV DEBIAN_FRONTEND noninteractive
|
||||
|
||||
RUN rm -r /etc/apt/sources.list.d/
|
||||
|
||||
RUN apt-get update -y && apt-get install -y \
|
||||
libgl1 libglib2.0-0 google-perftools \
|
||||
sudo wget git git-lfs vim tig pkg-config libcairo2-dev \
|
||||
aria2 telnet curl net-tools iputils-ping jq \
|
||||
python3-pip python-is-python3 python3.10-venv tzdata lsof zip tmux
|
||||
RUN apt-get update && \
|
||||
apt-get install -y software-properties-common && \
|
||||
add-apt-repository ppa:ubuntuhandbook1/ffmpeg6 && \
|
||||
apt-get update && \
|
||||
apt-get install -y ffmpeg
|
||||
|
||||
RUN pip3 install --upgrade pip -i https://mirrors.aliyun.com/pypi/simple/
|
||||
|
||||
# add all extensions
|
||||
RUN pip install wandb tqdm GitPython==3.1.32 Pillow==9.5.0 setuptools --upgrade -i https://mirrors.aliyun.com/pypi/simple/
|
||||
|
||||
RUN pip install torch==2.4.0 torchvision==0.19.0 torchaudio==2.4.0 --index-url https://download.pytorch.org/whl/cu118
|
||||
RUN pip install xformers==0.0.27.post2 --index-url https://download.pytorch.org/whl/cu118
|
||||
|
||||
# install vllm (video-caption)
|
||||
RUN pip install vllm==0.6.3
|
||||
|
||||
# install requirements (video-caption)
|
||||
WORKDIR /root/
|
||||
COPY easyanimate/video_caption/requirements.txt /root/requirements-video_caption.txt
|
||||
RUN pip install -r /root/requirements-video_caption.txt
|
||||
RUN rm /root/requirements-video_caption.txt
|
||||
|
||||
RUN pip install -U http://eas-data.oss-cn-shanghai.aliyuncs.com/sdk/allspark-0.15-py2.py3-none-any.whl
|
||||
RUN pip install -e git+https://github.com/CompVis/taming-transformers.git@master#egg=taming-transformers
|
||||
RUN pip install came-pytorch deepspeed pytorch_lightning==1.9.4 func_timeout -i https://mirrors.aliyun.com/pypi/simple/
|
||||
|
||||
# install requirements
|
||||
RUN pip install bitsandbytes mamba-ssm causal-conv1d>=1.4.0 -i https://mirrors.aliyun.com/pypi/simple/
|
||||
RUN pip install ipykernel -i https://mirrors.aliyun.com/pypi/simple/
|
||||
COPY ./requirements.txt /root/requirements.txt
|
||||
RUN pip install -r /root/requirements.txt -i https://mirrors.aliyun.com/pypi/simple/
|
||||
RUN rm -rf /root/requirements.txt
|
||||
|
||||
# install package patches (video-caption)
|
||||
COPY easyanimate/video_caption/package_patches/easyocr_detection_patched.py /usr/local/lib/python3.10/dist-packages/easyocr/detection.py
|
||||
COPY easyanimate/video_caption/package_patches/vila_siglip_encoder_patched.py /usr/local/lib/python3.10/dist-packages/llava/model/multimodal_encoder/siglip_encoder.py
|
||||
|
||||
ENV PYTHONUNBUFFERED 1
|
||||
ENV NVIDIA_DISABLE_REQUIRE 1
|
||||
|
||||
WORKDIR /root/
|
||||
@@ -1,60 +1,45 @@
|
||||
# VideoX-Fun
|
||||
# CogVideoX-Fun
|
||||
|
||||
😊 Welcome!
|
||||
|
||||
CogVideoX-Fun:
|
||||
[](https://huggingface.co/spaces/alibaba-pai/CogVideoX-Fun-5b)
|
||||
|
||||
Wan-Fun:
|
||||
[](https://huggingface.co/spaces/alibaba-pai/Wan2.1-Fun-1.3B-InP)
|
||||
|
||||
English | [简体中文](./README_zh-CN.md) | [日本語](./README_ja-JP.md)
|
||||
English | [简体中文](./README_zh-CN.md)
|
||||
|
||||
# Table of Contents
|
||||
- [Table of Contents](#table-of-contents)
|
||||
- [Introduction](#introduction)
|
||||
- [Quick Start](#quick-start)
|
||||
- [Video Result](#video-result)
|
||||
- [How to use](#how-to-use)
|
||||
- [Model zoo](#model-zoo)
|
||||
- [TODO List](#todo-list)
|
||||
- [Reference](#reference)
|
||||
- [License](#license)
|
||||
|
||||
# Introduction
|
||||
VideoX-Fun is a video generation pipeline that can be used to generate AI images and videos, as well as to train baseline and Lora models for Diffusion Transformer. We support direct prediction from pre-trained baseline models to generate videos with different resolutions, durations, and FPS. Additionally, we also support users in training their own baseline and Lora models to perform specific style transformations.
|
||||
CogVideoX-Fun is a modified pipeline based on the CogVideoX structure, designed to provide more flexibility in generation. It can be used to create AI images and videos, as well as to train baseline models and Lora models for Diffusion Transformer. We support predictions directly from the already trained CogVideoX-Fun model, allowing the generation of videos at different resolutions, approximately 6 seconds long with 8 fps (1 to 49 frames). Users can also train their own baseline models and Lora models to achieve certain style transformations.
|
||||
|
||||
We will support quick pull-ups from different platforms, refer to [Quick Start](#quick-start).
|
||||
|
||||
What's New:
|
||||
- Added support for Wan 2.2 series models, Wan-VACE control model, Fantasy Talking digital human model, Qwen-Image, Flux image generation models, and more. [2025.10.16]
|
||||
- Update Wan2.1-Fun-V1.1: Support for 14B and 1.3B model Control + Reference Image models, support for camera control, and the Inpaint model has been retrained for improved performance. [2025.04.25]
|
||||
- Update Wan2.1-Fun-V1.0: Support I2V and Control models for 14B and 1.3B models, with support for start and end frame prediction. [2025.03.26]
|
||||
- Update CogVideoX-Fun-V1.5: Upload I2V model and related training/prediction code. [2024.12.16]
|
||||
- Reward Lora Support: Train Lora using reward backpropagation techniques to optimize generated videos, making them better aligned with human preferences. [More Information](scripts/README_TRAIN_REWARD.md). New version of the control model supports various control conditions such as Canny, Depth, Pose, MLSD, etc. [2024.11.21]
|
||||
- Diffusers Support: CogVideoX-Fun Control is now supported in diffusers. Thanks to [a-r-r-o-w](https://github.com/a-r-r-o-w) for contributing support in this [PR](https://github.com/huggingface/diffusers/pull/9671). Check out the [documentation](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cogvideox) for more details. [2024.10.16]
|
||||
- Update CogVideoX-Fun-V1.1: Retrain i2v model, add Noise to increase the motion amplitude of the video. Upload control model training code and Control model. [2024.09.29]
|
||||
- Update CogVideoX-Fun-V1.0: Initial code release! Now supports Windows and Linux. Supports video generation at arbitrary resolutions from 256x256x49 to 1024x1024x49 for 2B and 5B models. [2024.09.18]
|
||||
- Create code! Now supporting Windows and Linux. Supports video generation at any resolution from 256x256x49 to 1024x1024x49. [ 2024.09.09 ]
|
||||
|
||||
Function:
|
||||
- [Data Preprocessing](#data-preprocess)
|
||||
- [Train DiT](#dit-train)
|
||||
- [Video Generation](#video-gen)
|
||||
|
||||
These are our generated results [GALLERY](scripts/Result_Gallery.md) (Click the image below to see the video):
|
||||
|
||||
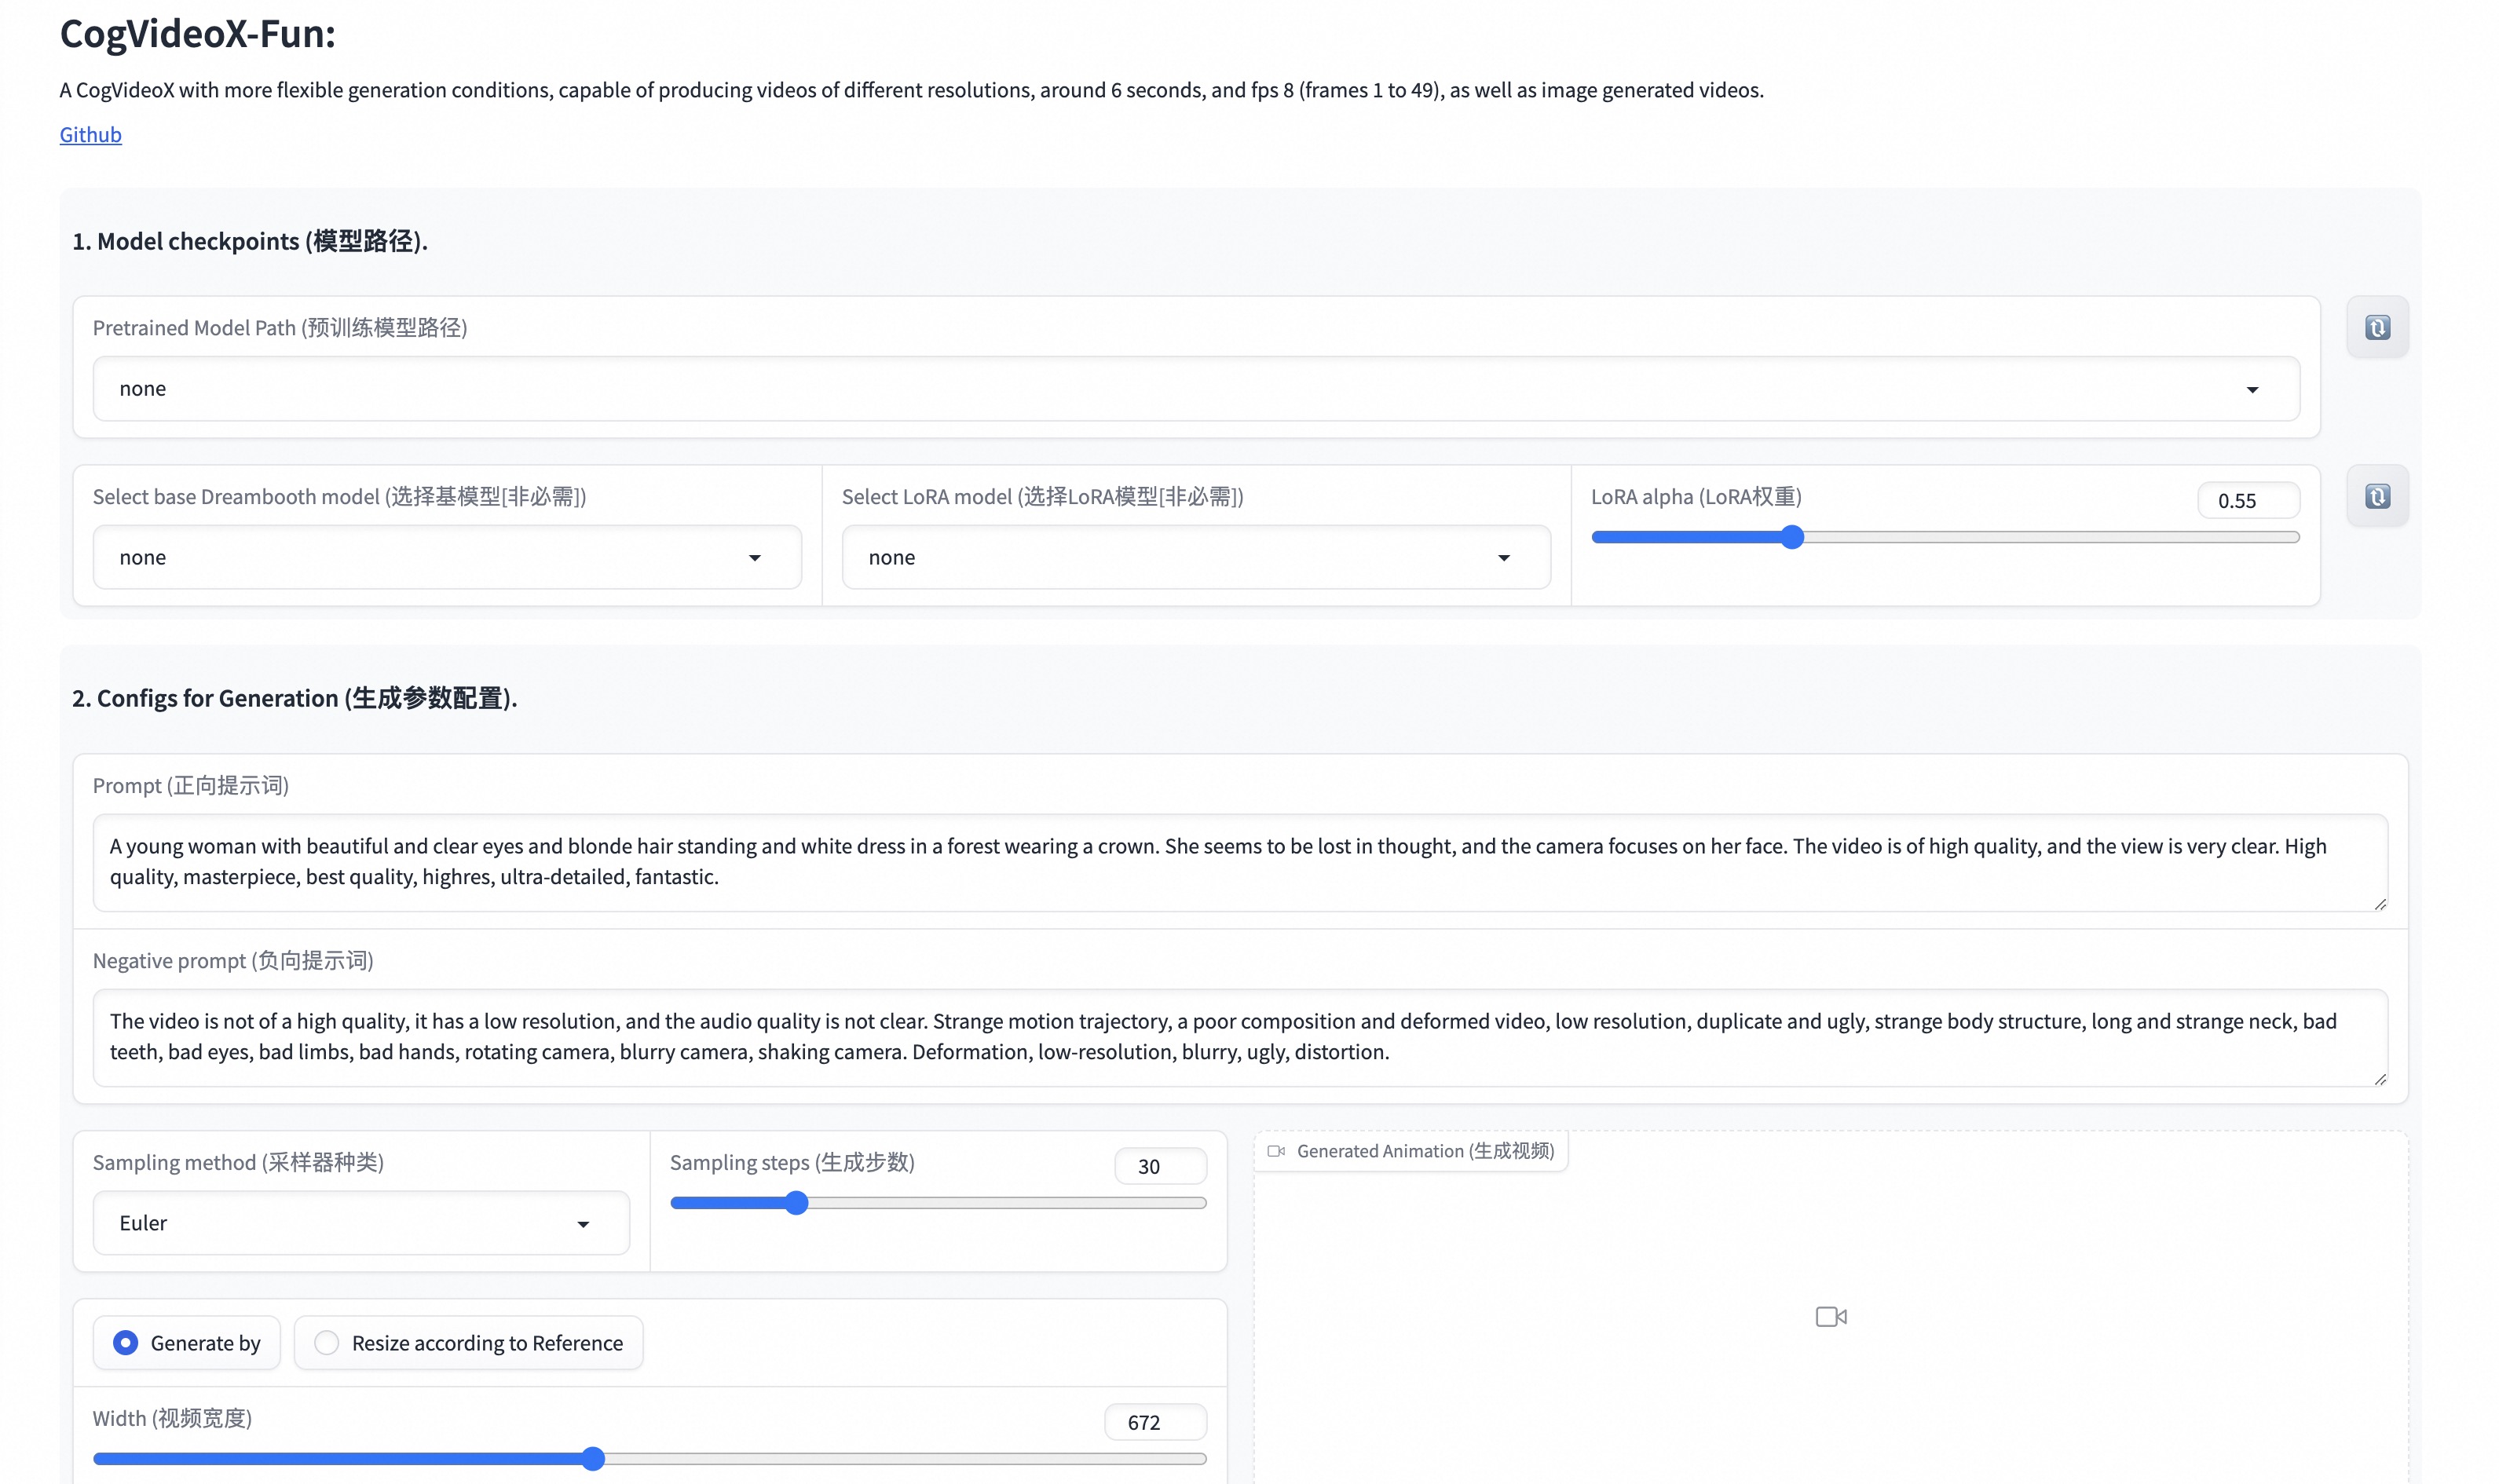
Our UI interface is as follows:
|
||||
|
||||
|
||||
# Quick Start
|
||||
### 1. Cloud usage: AliyunDSW/Docker
|
||||
#### a. From AliyunDSW
|
||||
DSW has free GPU time, which can be applied once by a user and is valid for 3 months after applying.
|
||||
|
||||
Aliyun provide free GPU time in [Freetier](https://free.aliyun.com/?product=9602825&crowd=enterprise&spm=5176.28055625.J_5831864660.1.e939154aRgha4e&scm=20140722.M_9974135.P_110.MO_1806-ID_9974135-MID_9974135-CID_30683-ST_8512-V_1), get it and use in Aliyun PAI-DSW to start CogVideoX-Fun within 5min!
|
||||
|
||||
[](https://gallery.pai-ml.com/#/preview/deepLearning/cv/cogvideox_fun)
|
||||
On the way.
|
||||
|
||||
#### b. From ComfyUI
|
||||
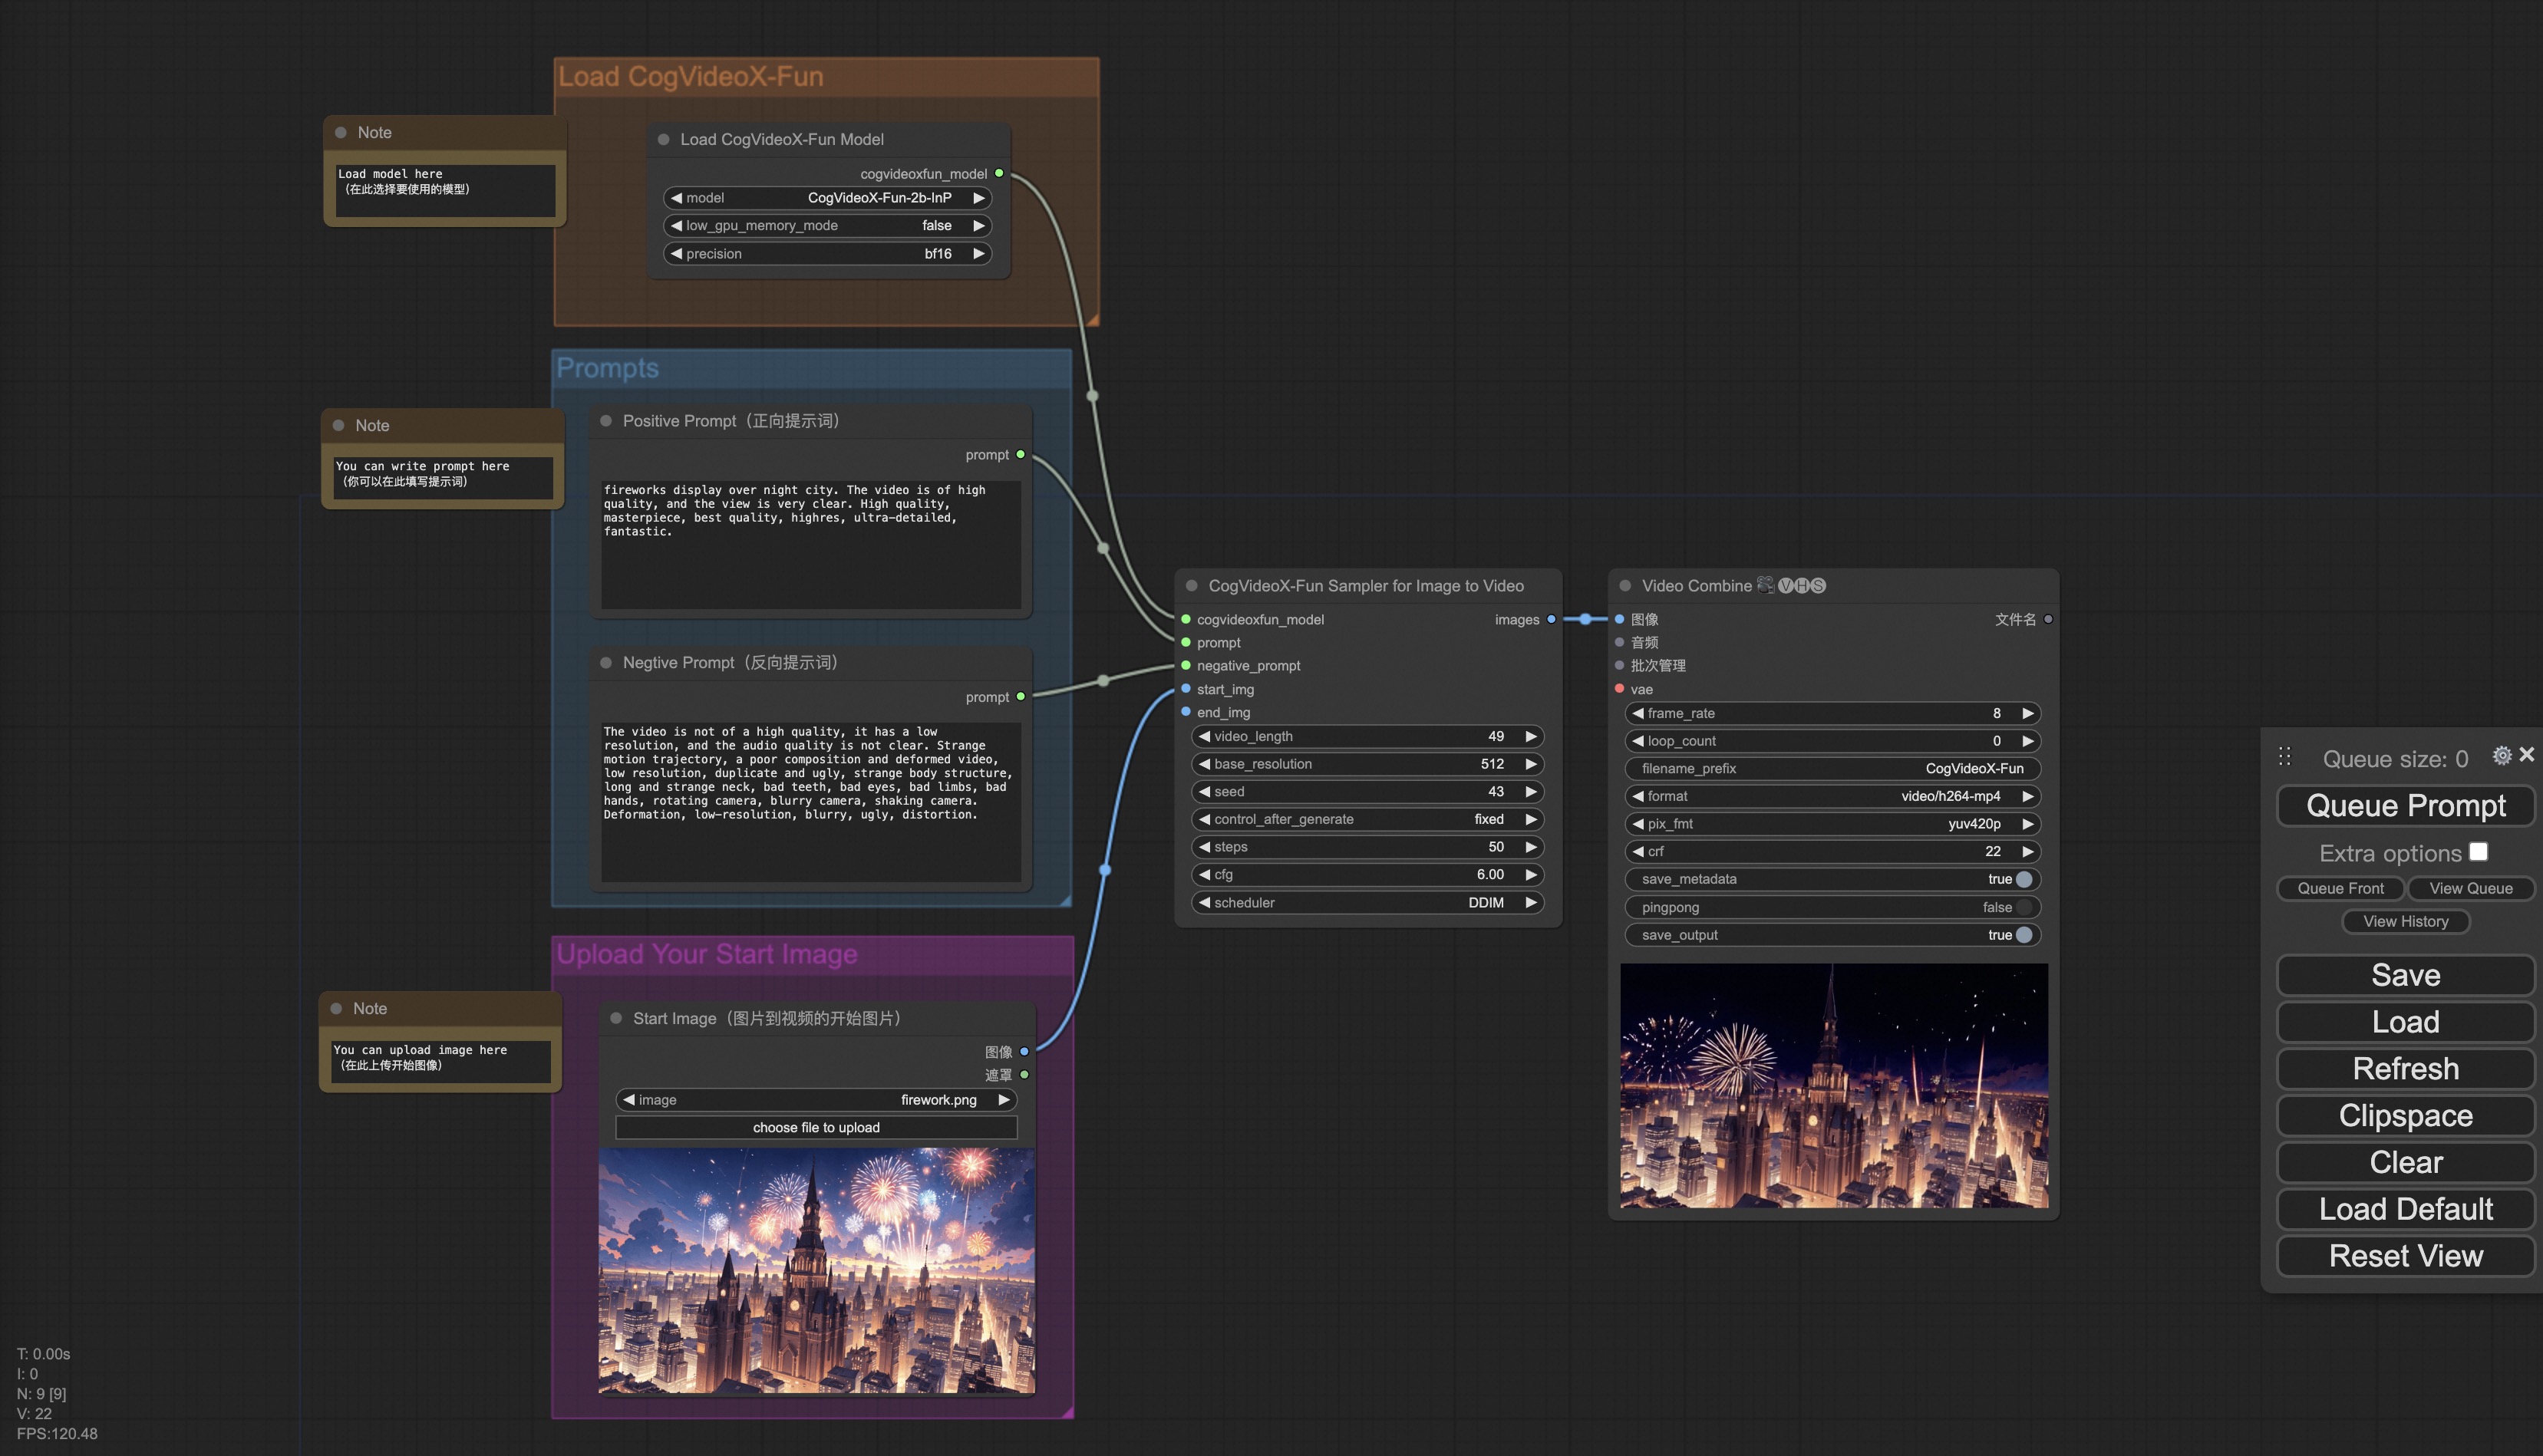
Our ComfyUI is as follows, please refer to [ComfyUI README](comfyui/README.md) for details.
|
||||
|
||||

|
||||
|
||||
#### c. From docker
|
||||
If you are using docker, please make sure that the graphics card driver and CUDA environment have been installed correctly in your machine.
|
||||
@@ -69,28 +54,25 @@ docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cud
|
||||
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# clone code
|
||||
git clone https://github.com/aigc-apps/VideoX-Fun.git
|
||||
git clone https://github.com/aigc-apps/CogVideoX-Fun.git
|
||||
|
||||
# enter VideoX-Fun's dir
|
||||
cd VideoX-Fun
|
||||
# enter CogVideoX-Fun's dir
|
||||
cd CogVideoX-Fun
|
||||
|
||||
# download weights
|
||||
mkdir models/Diffusion_Transformer
|
||||
mkdir models/Personalized_Model
|
||||
|
||||
# Please use the hugginface link or modelscope link to download the model.
|
||||
# CogVideoX-Fun
|
||||
# https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP
|
||||
# https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP
|
||||
wget https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz -O models/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz
|
||||
|
||||
# Wan
|
||||
# https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP
|
||||
# https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP
|
||||
cd models/Diffusion_Transformer/
|
||||
tar -xvf CogVideoX-Fun-2b-InP.tar.gz
|
||||
cd ../../
|
||||
```
|
||||
|
||||
### 2. Local install: Environment Check/Downloading/Installation
|
||||
#### a. Environment Check
|
||||
We have verified this repo execution on the following environment:
|
||||
We have verified CogVideoX-Fun execution on the following environment:
|
||||
|
||||
The detailed of Windows:
|
||||
- OS: Windows 10
|
||||
@@ -113,358 +95,34 @@ We need about 60GB available on disk (for saving weights), please check!
|
||||
#### b. Weights
|
||||
We'd better place the [weights](#model-zoo) along the specified path:
|
||||
|
||||
**Via ComfyUI**:
|
||||
Put the models into the ComfyUI weights folder `ComfyUI/models/Fun_Models/`:
|
||||
```
|
||||
📦 ComfyUI/
|
||||
├── 📂 models/
|
||||
│ └── 📂 Fun_Models/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
|
||||
│ ├── 📂 Wan2.1-Fun-14B-InP
|
||||
│ └── 📂 Wan2.1-Fun-1.3B-InP/
|
||||
```
|
||||
|
||||
**Run its own python file or UI interface**:
|
||||
```
|
||||
📦 models/
|
||||
├── 📂 Diffusion_Transformer/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
|
||||
│ ├── 📂 Wan2.1-Fun-14B-InP
|
||||
│ └── 📂 Wan2.1-Fun-1.3B-InP/
|
||||
│ └── 📂 CogVideoX-Fun-2b-InP/
|
||||
├── 📂 Personalized_Model/
|
||||
│ └── your trained trainformer model / your trained lora model (for UI load)
|
||||
```
|
||||
|
||||
# Video Result
|
||||
# How to use
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-InP && Wan2.1-Fun-V1.1-1.3B-InP
|
||||
<h3 id="video-gen">1. Inference </h3>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
#### a. Using Python Code
|
||||
- Step 1: Download the corresponding [weights](#model-zoo) and place them in the models folder.
|
||||
- Step 2: Modify prompt, neg_prompt, guidance_scale, and seed in the predict_t2v.py file.
|
||||
- Step 3: Run the predict_t2v.py file, wait for the generated results, and save the results in the samples/cogvideox-fun-videos-t2v folder.
|
||||
- Step 4: If you want to combine other backbones you have trained with Lora, modify the predict_t2v.py and Lora_path in predict_t2v.py depending on the situation.
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
#### b. Using webui
|
||||
- Step 1: Download the corresponding [weights](#model-zoo) and place them in the models folder.
|
||||
- Step 2: Run the app.py file to enter the graph page.
|
||||
- Step 3: Select the generated model based on the page, fill in prompt, neg_prompt, guidance_scale, and seed, click on generate, wait for the generated result, and save the result in the samples folder.
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
|
||||
|
||||
Generic Control Video + Reference Image:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Reference Image
|
||||
</td>
|
||||
<td>
|
||||
Control Video
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-14B-Control
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-1.3B-Control
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</table>
|
||||
|
||||
|
||||
Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</table>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Pan Up
|
||||
</td>
|
||||
<td>
|
||||
Pan Left
|
||||
</td>
|
||||
<td>
|
||||
Pan Right
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
Pan Down
|
||||
</td>
|
||||
<td>
|
||||
Pan Up + Pan Left
|
||||
</td>
|
||||
<td>
|
||||
Pan Up + Pan Right
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B
|
||||
|
||||
Resolution-1024
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
Resolution-768
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
Resolution-512
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B-Control
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
A young woman with beautiful clear eyes and blonde hair, wearing white clothes and twisting her body, with the camera focused on her face. High quality, masterpiece, best quality, high resolution, ultra-fine, dreamlike.
|
||||
</td>
|
||||
<td>
|
||||
A young woman with beautiful clear eyes and blonde hair, wearing white clothes and twisting her body, with the camera focused on her face. High quality, masterpiece, best quality, high resolution, ultra-fine, dreamlike.
|
||||
</td>
|
||||
<td>
|
||||
A young bear.
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
# How to Use
|
||||
|
||||
<h3 id="video-gen">1. Generation</h3>
|
||||
|
||||
#### a. GPU Memory Optimization
|
||||
Since Wan2.1 has a very large number of parameters, we need to consider memory optimization strategies to adapt to consumer-grade GPUs. We provide `GPU_memory_mode` for each prediction file, allowing you to choose between `model_cpu_offload`, `model_cpu_offload_and_qfloat8`, and `sequential_cpu_offload`. This solution is also applicable to CogVideoX-Fun generation.
|
||||
|
||||
- `model_cpu_offload`: The entire model is moved to the CPU after use, saving some GPU memory.
|
||||
- `model_cpu_offload_and_qfloat8`: The entire model is moved to the CPU after use, and the transformer model is quantized to float8, saving more GPU memory.
|
||||
- `sequential_cpu_offload`: Each layer of the model is moved to the CPU after use. It is slower but saves a significant amount of GPU memory.
|
||||
|
||||
`qfloat8` may slightly reduce model performance but saves more GPU memory. If you have sufficient GPU memory, it is recommended to use `model_cpu_offload`.
|
||||
|
||||
#### b. Using ComfyUI
|
||||
For details, refer to [ComfyUI README](comfyui/README.md).
|
||||
|
||||
#### c. Running Python Files
|
||||
|
||||
##### i. Single-GPU Inference:
|
||||
|
||||
- **Step 1**: Download the corresponding [weights](#model-zoo) and place them in the `models` folder.
|
||||
- **Step 2**: Use different files for prediction based on the weights and prediction goals. This library currently supports CogVideoX-Fun, Wan2.1, and Wan2.1-Fun. Different models are distinguished by folder names under the `examples` folder, and their supported features vary. Use them accordingly. Below is an example using CogVideoX-Fun:
|
||||
- **Text-to-Video**:
|
||||
- Modify `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_t2v.py`.
|
||||
- Run the file `examples/cogvideox_fun/predict_t2v.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos`.
|
||||
- **Image-to-Video**:
|
||||
- Modify `validation_image_start`, `validation_image_end`, `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_i2v.py`.
|
||||
- `validation_image_start` is the starting image of the video, and `validation_image_end` is the ending image of the video.
|
||||
- Run the file `examples/cogvideox_fun/predict_i2v.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos_i2v`.
|
||||
- **Video-to-Video**:
|
||||
- Modify `validation_video`, `validation_image_end`, `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_v2v.py`.
|
||||
- `validation_video` is the reference video for video-to-video generation. You can use the following demo video: [Demo Video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/play_guitar.mp4).
|
||||
- Run the file `examples/cogvideox_fun/predict_v2v.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos_v2v`.
|
||||
- **Controlled Video Generation (Canny, Pose, Depth, etc.)**:
|
||||
- Modify `control_video`, `validation_image_end`, `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_v2v_control.py`.
|
||||
- `control_video` is the control video extracted using operators such as Canny, Pose, or Depth. You can use the following demo video: [Demo Video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/pose.mp4).
|
||||
- Run the file `examples/cogvideox_fun/predict_v2v_control.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos_v2v_control`.
|
||||
- **Step 3**: If you want to integrate other backbones or Loras trained by yourself, modify `lora_path` and relevant paths in `examples/{model_name}/predict_t2v.py` or `examples/{model_name}/predict_i2v.py` as needed.
|
||||
|
||||
##### ii. Multi-GPU Inference:
|
||||
When using multi-GPU inference, please make sure to install the xfuser. We recommend installing xfuser==0.4.2 and yunchang==0.6.2.
|
||||
```
|
||||
pip install xfuser==0.4.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
pip install yunchang==0.6.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
```
|
||||
|
||||
Please ensure that the product of `ulysses_degree` and `ring_degree` equals the number of GPUs being used. For example, if you are using 8 GPUs, you can set `ulysses_degree=2` and `ring_degree=4`, or alternatively `ulysses_degree=4` and `ring_degree=2`.
|
||||
|
||||
- `ulysses_degree` performs parallelization after splitting across the heads.
|
||||
- `ring_degree` performs parallelization after splitting across the sequence.
|
||||
|
||||
Compared to `ulysses_degree`, `ring_degree` incurs higher communication costs. Therefore, when setting these parameters, you should take into account both the sequence length and the number of heads in the model.
|
||||
|
||||
Let’s take 8-GPU parallel inference as an example:
|
||||
|
||||
- **For Wan2.1-Fun-V1.1-14B-InP**, which has 40 heads, `ulysses_degree` should be set to a divisor of 40 (e.g., 2, 4, 8, etc.). Thus, when using 8 GPUs for parallel inference, you can set `ulysses_degree=8` and `ring_degree=1`.
|
||||
|
||||
- **For Wan2.1-Fun-V1.1-1.3B-InP**, which has 12 heads, `ulysses_degree` should be set to a divisor of 12 (e.g., 2, 4, etc.). Thus, when using 8 GPUs for parallel inference, you can set `ulysses_degree=4` and `ring_degree=2`.
|
||||
|
||||
After setting the parameters, run the following command for parallel inference:
|
||||
|
||||
```sh
|
||||
torchrun --nproc-per-node=8 examples/wan2.1_fun/predict_t2v.py
|
||||
```
|
||||
|
||||
#### d. Using the Web UI
|
||||
The web UI supports text-to-video, image-to-video, video-to-video, and controlled video generation (Canny, Pose, Depth, etc.). This library currently supports CogVideoX-Fun, Wan2.1, and Wan2.1-Fun. Different models are distinguished by folder names under the `examples` folder, and their supported features vary. Use them accordingly. Below is an example using CogVideoX-Fun:
|
||||
|
||||
- **Step 1**: Download the corresponding [weights](#model-zoo) and place them in the `models` folder.
|
||||
- **Step 2**: Run the file `examples/cogvideox_fun/app.py` to access the Gradio interface.
|
||||
- **Step 3**: Select the generation model on the page, fill in `prompt`, `neg_prompt`, `guidance_scale`, and `seed`, click "Generate," and wait for the results. The generated videos will be saved in the `sample` folder.
|
||||
#### c. From ComfyUI
|
||||
Please refer to [ComfyUI README](comfyui/README.md) for details.
|
||||
|
||||
### 2. Model Training
|
||||
A complete model training pipeline should include data preprocessing and Video DiT training. The training process for different models is similar, and the data formats are also similar:
|
||||
A complete CogVideoX-Fun training pipeline should include data preprocessing, and Video DiT training.
|
||||
|
||||
<h4 id="data-preprocess">a. data preprocessing</h4>
|
||||
|
||||
@@ -521,7 +179,7 @@ You can also set the path as absolute path as follow:
|
||||
|
||||
<h4 id="dit-train">b. Video DiT training </h4>
|
||||
|
||||
If the data format is relative path during data preprocessing, please set ```scripts/{model_name}/train.sh``` as follow.
|
||||
If the data format is relative path during data preprocessing, please set ```scripts/train.sh``` as follow.
|
||||
```
|
||||
export DATASET_NAME="datasets/internal_datasets/"
|
||||
export DATASET_META_NAME="datasets/internal_datasets/json_of_internal_datasets.json"
|
||||
@@ -538,170 +196,23 @@ Then, we run scripts/train.sh.
|
||||
sh scripts/train.sh
|
||||
```
|
||||
|
||||
For details on some parameter settings:
|
||||
Wan2.1-Fun can be found in [Readme Train](scripts/wan2.1_fun/README_TRAIN.md) and [Readme Lora](scripts/wan2.1_fun/README_TRAIN_LORA.md).
|
||||
Wan2.1 can be found in [Readme Train](scripts/wan2.1/README_TRAIN.md) and [Readme Lora](scripts/wan2.1/README_TRAIN_LORA.md).
|
||||
CogVideoX-Fun can be found in [Readme Train](scripts/cogvideox_fun/README_TRAIN.md) and [Readme Lora](scripts/cogvideox_fun/README_TRAIN_LORA.md).
|
||||
For details on setting some parameters, please refer to [Readme Train](scripts/README_TRAIN.md) and [Readme Lora](scripts/README_TRAIN_LORA.md).
|
||||
|
||||
|
||||
# Model zoo
|
||||
## 1. Wan2.2-Fun
|
||||
|
||||
| Name | Storage Size | Hugging Face | Model Scope | Description |
|
||||
| Name | Storage Space | Url | Hugging Face | Description |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.2-Fun-A14B-InP | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-InP) | Wan2.2-Fun-14B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
|
||||
| Wan2.2-Fun-A14B-Control | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control)| Wan2.2-Fun-14B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support. |
|
||||
| Wan2.2-Fun-A14B-Control-Camera | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control-Camera)| Wan2.2-Fun-14B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
| Wan2.2-VACE-Fun-A14B | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-VACE-Fun-A14B) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-VACE-Fun-A14B) | Control weights for Wan2.2 trained using the VACE scheme (based on the base model Wan2.2-T2V-A14B), supporting various control conditions such as Canny, Depth, Pose, MLSD, trajectory control, etc. It supports video generation by specifying the subject. It supports multi-resolution (512, 768, 1024) video prediction, and is trained with 81 frames at 16 FPS. It also supports multi-language prediction. |
|
||||
| Wan2.2-Fun-5B-InP | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-InP) | Wan2.2-Fun-5B text-to-video weights trained at 121 frames, 24 FPS, supporting first/last frame prediction. |
|
||||
| Wan2.2-Fun-5B-Control | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control)| Wan2.2-Fun-5B video control weights, supporting control conditions like Canny, Depth, Pose, MLSD, and trajectory control. Trained at 121 frames, 24 FPS, with multilingual prediction support. |
|
||||
| Wan2.2-Fun-5B-Control-Camera | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control-Camera)| Wan2.2-Fun-5B camera lens control weights. Trained at 121 frames, 24 FPS, with multilingual prediction support. |
|
||||
| CogVideoX-Fun-2b-InP.tar.gz | Before extraction:9.69 GB \/ After extraction: 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 144 frames at a rate of 24 frames per second. |
|
||||
|
||||
|
||||
## 2. Wan2.2
|
||||
|
||||
| Name | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|
|
||||
| Wan2.2-TI2V-5B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-TI2V-5B) | Wan2.2-5B Text-to-Video Weights |
|
||||
| Wan2.2-T2V-14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-T2V-A14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-T2V-A14B) | Wan2.2-14B Text-to-Video Weights |
|
||||
| Wan2.2-I2V-A14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-I2V-A14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-I2V-A14B) | Wan2.2-I2V-A14B Image-to-Video Weights |
|
||||
|
||||
## 3. Wan2.1-Fun
|
||||
|
||||
V1.1:
|
||||
| Name | Storage Size | Hugging Face | Model Scope | Description |
|
||||
|------|--------------|--------------|-------------|-------------|
|
||||
| Wan2.1-Fun-V1.1-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP) | Wan2.1-Fun-V1.1-1.3B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
|
||||
| Wan2.1-Fun-V1.1-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP) | Wan2.1-Fun-V1.1-14B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control) | Wan2.1-Fun-V1.1-1.3B video control weights support various control conditions such as Canny, Depth, Pose, MLSD, etc., supports reference image + control condition-based control, and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control) | Wan2.1-Fun-V1.1-14B video control weights support various control conditions such as Canny, Depth, Pose, MLSD, etc., supports reference image + control condition-based control, and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control-Camera | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control-Camera) | Wan2.1-Fun-V1.1-1.3B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
| Wan2.1-Fun-V1.1-14B-Control-Camera | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control-Camera) | Wan2.1-Fun-V1.1-14B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
|
||||
V1.0:
|
||||
| Name | Storage Space | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-InP) | Wan2.1-Fun-1.3B text-to-video weights, trained at multiple resolutions, supporting start and end frame prediction. |
|
||||
| Wan2.1-Fun-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP) | Wan2.1-Fun-14B text-to-video weights, trained at multiple resolutions, supporting start and end frame prediction. |
|
||||
| Wan2.1-Fun-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-Control) | Wan2.1-Fun-1.3B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support. |
|
||||
| Wan2.1-Fun-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-Control) | Wan2.1-Fun-14B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support. |
|
||||
|
||||
## 4. Wan2.1
|
||||
|
||||
| Name | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|
|
||||
| Wan2.1-T2V-1.3B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-1.3B) | Wanxiang 2.1-1.3B text-to-video weights |
|
||||
| Wan2.1-T2V-14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-14B) | Wanxiang 2.1-14B text-to-video weights |
|
||||
| Wan2.1-I2V-14B-480P | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-480P) | Wanxiang 2.1-14B-480P image-to-video weights |
|
||||
| Wan2.1-I2V-14B-720P| [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | Wanxiang 2.1-14B-720P image-to-video weights |
|
||||
|
||||
## 5. FantasyTalking
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-I2V-14B-720P | - | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | Wan 2.1-14B-720P image-to-video model weights |
|
||||
| Wav2Vec | - | [🤗Link](https://huggingface.co/facebook/wav2vec2-base-960h) | [😄Link](https://modelscope.cn/models/AI-ModelScope/wav2vec2-base-960h) | Wav2Vec model; place inside the Wan2.1-I2V-14B-720P folder and rename to `audio_encoder` |
|
||||
| FantasyTalking model | - | [🤗Link](https://huggingface.co/acvlab/FantasyTalking/) | [😄Link](https://www.modelscope.cn/models/amap_cvlab/FantasyTalking/) | Official audio-conditioned weights |
|
||||
|
||||
## 6. Qwen-Image
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image | [🤗Link](https://huggingface.co/Qwen/Qwen-Image) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image) | Official Qwen-Image weights |
|
||||
| Qwen-Image-Edit | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit) | Official Qwen-Image-Edit weights |
|
||||
| Qwen-Image-Edit-2509 | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit-2509) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509) | Official Qwen-Image-Edit-2509 weights |
|
||||
|
||||
## 7. Qwen-Image-Fun
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image-2512-Fun-Controlnet-Union | - | [🤗Link](https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union) | [😄Link](https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union) | ControlNet weights for Qwen-Image-2512, supporting multiple control conditions such as Canny, Depth, Pose, MLSD, Scribble, etc. |
|
||||
|
||||
## 8. Z-Image
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image | [🤗Link](https://huggingface.co/Tongyi-MAI/Z-Image) | [😄Link](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image) | Official weights for Z-Image |
|
||||
| Z-Image-Turbo | [🤗Link](https://huggingface.co/Tongyi-MAI/Z-Image-Turbo) | [😄Link](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo) | Official weights for Z-Image-Turbo |
|
||||
|
||||
## 9. Z-Image-Fun
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image-Fun-Controlnet-Union-2.1 | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1) | ControlNet weights for Z-Image. Compared to the first version, it adds to more layers and has been trained for a longer period. It supports multiple control conditions including Canny, Depth, Pose, MLSD, Scribble and Gray. |
|
||||
| Z-Image-Fun-Lora-Distill | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill) | This is a Distill LoRA for Z-Image that distills both steps and CFG. This model does not require CFG and uses 8 steps for inference. |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union) | ControlNet weights for Z-Image-Turbo, supporting multiple control conditions such as Canny, Depth, Pose, MLSD, etc. |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union-2.1 | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | ControlNet weights for Z-Image-Turbo. Compared to the first version, it adds to more layers and has been trained for a longer period. It supports multiple control conditions including Canny, Depth, Pose, MLSD, and more. |
|
||||
|
||||
## 10. Flux
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| FLUX.1-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.1-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev) | Official FLUX.1-dev weights |
|
||||
| FLUX.2-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.2-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev) | Official FLUX.2-dev weights |
|
||||
|
||||
## 11. Flux-Fun
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Flux.2-dev-Fun-Controlnet-Union | - | [🤗Link](https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union) | [😄Link](https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union) | Flux.2-dev control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc. |
|
||||
|
||||
## 12. HunyuanVideo
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| HunyuanVideo | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo) | - | HunyuanVideo-diffusers weights |
|
||||
| HunyuanVideo-I2V | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo-I2V) | - | HunyuanVideo-I2V-diffusers weights |
|
||||
|
||||
## 13. CogVideoX-Fun
|
||||
|
||||
V1.5:
|
||||
|
||||
| Name | Storage Space | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.5-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-5b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024) and has been trained on 85 frames at a rate of 8 frames per second. |
|
||||
| CogVideoX-Fun-V1.5-Reward-LoRAs | - | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs) | The official reward backpropagation technology model optimizes the videos generated by CogVideoX-Fun-V1.5 to better match human preferences. |
|
||||
|
||||
V1.1:
|
||||
|
||||
| Name | Storage Space | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.1-2b-InP | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. |
|
||||
| CogVideoX-Fun-V1.1-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Noise has been added to the reference image, and the amplitude of motion is greater compared to V1.0. |
|
||||
| CogVideoX-Fun-V1.1-2b-Pose | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Pose) | Our official pose-control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second.|
|
||||
| CogVideoX-Fun-V1.1-2b-Control | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Control) | Our official control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Supporting various control conditions such as Canny, Depth, Pose, MLSD, etc.|
|
||||
| CogVideoX-Fun-V1.1-5b-Pose | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Pose) | Our official pose-control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second.|
|
||||
| CogVideoX-Fun-V1.1-5b-Control | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Control) | Our official control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Supporting various control conditions such as Canny, Depth, Pose, MLSD, etc.|
|
||||
| CogVideoX-Fun-V1.1-Reward-LoRAs | - | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-Reward-LoRAs) | The official reward backpropagation technology model optimizes the videos generated by CogVideoX-Fun-V1.1 to better match human preferences. |
|
||||
|
||||
<details>
|
||||
<summary>(Obsolete) V1.0:</summary>
|
||||
|
||||
| Name | Storage Space | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-2b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. |
|
||||
| CogVideoX-Fun-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP)| [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-5b-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. |
|
||||
</details>
|
||||
# TODO List
|
||||
- Support CogVideoX-5b.
|
||||
|
||||
# Reference
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
|
||||
- Wan2.1: https://github.com/Wan-Video/Wan2.1/
|
||||
- Wan2.2: https://github.com/Wan-Video/Wan2.2/
|
||||
- Diffusers: https://github.com/huggingface/diffusers
|
||||
- Qwen-Image: https://github.com/QwenLM/Qwen-Image
|
||||
- Self-Forcing: https://github.com/guandeh17/Self-Forcing
|
||||
- Flux: https://github.com/black-forest-labs/flux
|
||||
- Flux2: https://github.com/black-forest-labs/flux2
|
||||
- HunyuanVideo: https://github.com/Tencent-Hunyuan/HunyuanVideo
|
||||
- ComfyUI-KJNodes: https://github.com/kijai/ComfyUI-KJNodes
|
||||
- ComfyUI-EasyAnimateWrapper: https://github.com/kijai/ComfyUI-EasyAnimateWrapper
|
||||
- ComfyUI-CameraCtrl-Wrapper: https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper
|
||||
- CameraCtrl: https://github.com/hehao13/CameraCtrl
|
||||
|
||||
# License
|
||||
This project is licensed under the [Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE).
|
||||
|
||||
The CogVideoX-2B model (including its corresponding Transformers module and VAE module) is released under the [Apache 2.0 License](LICENSE).
|
||||
|
||||
The CogVideoX-5B model (Transformers module) is released under the [CogVideoX LICENSE](https://huggingface.co/THUDM/CogVideoX-5b/blob/main/LICENSE).
|
||||
The CogVideoX-2B model (including its corresponding Transformers module and VAE module) is released under the [Apache 2.0 License](LICENSE).
|
||||
@@ -1,707 +0,0 @@
|
||||
# VideoX-Fun
|
||||
|
||||
😊 ようこそ!
|
||||
|
||||
CogVideoX-Fun:
|
||||
[](https://huggingface.co/spaces/alibaba-pai/CogVideoX-Fun-5b)
|
||||
|
||||
Wan-Fun:
|
||||
[](https://huggingface.co/spaces/alibaba-pai/Wan2.1-Fun-1.3B-InP)
|
||||
|
||||
[English](./README.md) | [简体中文](./README_zh-CN.md) | 日本語
|
||||
|
||||
# 目次
|
||||
- [目次](#目次)
|
||||
- [紹介](#紹介)
|
||||
- [クイックスタート](#クイックスタート)
|
||||
- [ビデオ結果](#ビデオ結果)
|
||||
- [使用方法](#使用方法)
|
||||
- [モデルの場所](#モデルの場所)
|
||||
- [参考文献](#参考文献)
|
||||
- [ライセンス](#ライセンス)
|
||||
|
||||
# 紹介
|
||||
VideoX-Funはビデオ生成のパイプラインであり、AI画像やビデオの生成、Diffusion TransformerのベースラインモデルとLoraモデルのトレーニングに使用できます。我々は、すでに学習済みのベースラインモデルから直接予測を行い、異なる解像度、秒数、FPSのビデオを生成することをサポートしています。また、ユーザーが独自のベースラインモデルやLoraモデルをトレーニングし、特定のスタイル変換を行うこともサポートしています。
|
||||
|
||||
異なるプラットフォームからのクイックスタートをサポートします。詳細は[クイックスタート](#クイックスタート)を参照してください。
|
||||
|
||||
新機能:
|
||||
- Wan 2.2シリーズモデル、Wan-VACE制御モデル、Fantasy Talkingデジタルヒューマンモデル、Qwen-Image、Flux画像生成モデルなどのサポートを追加しました。[2025.10.16]
|
||||
- Wan2.1-Fun-V1.1バージョンを更新:14Bと1.3BモデルのControl+参照画像モデルをサポート、カメラ制御にも対応。さらに、Inpaintモデルを再訓練し、性能が向上しました。[2025.04.25]
|
||||
- Wan2.1-Fun-V1.0の更新:14Bおよび1.3BのI2V(画像からビデオ)モデルとControlモデルをサポートし、開始フレームと終了フレームの予測に対応。[2025.03.26]
|
||||
- CogVideoX-Fun-V1.5の更新:I2Vモデルと関連するトレーニング・予測コードをアップロード。[2024.12.16]
|
||||
- 報酬Loraのサポート:報酬逆伝播技術を使用してLoraをトレーニングし、生成された動画を最適化し、人間の好みによりよく一致させる。[詳細情報](scripts/README_TRAIN_REWARD.md)。新しいバージョンの制御モデルでは、Canny、Depth、Pose、MLSDなどの異なる制御条件に対応。[2024.11.21]
|
||||
- diffusersのサポート:CogVideoX-Fun Controlがdiffusersでサポートされるようになりました。[a-r-r-o-w](https://github.com/a-r-r-o-w)がこの[PR](https://github.com/huggingface/diffusers/pull/9671)でサポートを提供してくれたことに感謝します。詳細は[ドキュメント](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cogvideox)をご覧ください。[2024.10.16]
|
||||
- CogVideoX-Fun-V1.1の更新:i2vモデルを再トレーニングし、Noiseを追加して動画の動きの範囲を拡大。制御モデルのトレーニングコードとControlモデルをアップロード。[2024.09.29]
|
||||
- CogVideoX-Fun-V1.0の更新:コードを作成!WindowsとLinuxに対応しました。2Bおよび5Bモデルでの最大256x256x49から1024x1024x49までの任意の解像度の動画生成をサポート。[2024.09.18]
|
||||
|
||||
機能:
|
||||
- [データ前処理](#data-preprocess)
|
||||
- [DiTのトレーニング](#dit-train)
|
||||
- [ビデオ生成](#video-gen)
|
||||
|
||||
私たちのUIインターフェースは次のとおりです:
|
||||

|
||||
|
||||
# クイックスタート
|
||||
### 1. クラウド使用: AliyunDSW/Docker
|
||||
#### a. AliyunDSWから
|
||||
DSWには無料のGPU時間があり、ユーザーは一度申請でき、申請後3か月間有効です。
|
||||
|
||||
Aliyunは[Freetier](https://free.aliyun.com/?product=9602825&crowd=enterprise&spm=5176.28055625.J_5831864660.1.e939154aRgha4e&scm=20140722.M_9974135.P_110.MO_1806-ID_9974135-MID_9974135-CID_30683-ST_8512-V_1)で無料のGPU時間を提供しています。取得してAliyun PAI-DSWで使用し、5分以内にCogVideoX-Funを開始できます!
|
||||
|
||||
[](https://gallery.pai-ml.com/#/preview/deepLearning/cv/cogvideox_fun)
|
||||
|
||||
#### b. ComfyUIから
|
||||
私たちのComfyUIは次のとおりです。詳細は[ComfyUI README](comfyui/README.md)を参照してください。
|
||||

|
||||
|
||||
#### c. Dockerから
|
||||
Dockerを使用する場合、マシンにグラフィックスカードドライバとCUDA環境が正しくインストールされていることを確認してください。
|
||||
|
||||
次のコマンドをこの方法で実行します:
|
||||
|
||||
```
|
||||
# イメージをプル
|
||||
docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# イメージに入る
|
||||
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# コードをクローン
|
||||
git clone https://github.com/aigc-apps/VideoX-Fun.git
|
||||
|
||||
# VideoX-Funのディレクトリに入る
|
||||
cd VideoX-Fun
|
||||
|
||||
# 重みをダウンロード
|
||||
mkdir models/Diffusion_Transformer
|
||||
mkdir models/Personalized_Model
|
||||
|
||||
# Please use the hugginface link or modelscope link to download the model.
|
||||
# CogVideoX-Fun
|
||||
# https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP
|
||||
# https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP
|
||||
|
||||
# Wan
|
||||
# https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP
|
||||
# https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP
|
||||
```
|
||||
|
||||
### 2. ローカルインストール: 環境チェック/ダウンロード/インストール
|
||||
#### a. 環境チェック
|
||||
以下の環境でこのライブラリの実行を確認しています:
|
||||
|
||||
Windowsの詳細:
|
||||
- OS: Windows 10
|
||||
- python: python3.10 & python3.11
|
||||
- pytorch: torch2.2.0
|
||||
- CUDA: 11.8 & 12.1
|
||||
- CUDNN: 8+
|
||||
- GPU: Nvidia-3060 12G & Nvidia-3090 24G
|
||||
|
||||
Linuxの詳細:
|
||||
- OS: Ubuntu 20.04, CentOS
|
||||
- python: python3.10 & python3.11
|
||||
- pytorch: torch2.2.0
|
||||
- CUDA: 11.8 & 12.1
|
||||
- CUDNN: 8+
|
||||
- GPU:Nvidia-V100 16G & Nvidia-A10 24G & Nvidia-A100 40G & Nvidia-A100 80G
|
||||
|
||||
重みを保存するために約60GBのディスクスペースが必要です。確認してください!
|
||||
|
||||
#### b. 重み
|
||||
[重み](#model-zoo)を指定されたパスに配置することをお勧めします:
|
||||
|
||||
**ComfyUIを通じて**:
|
||||
モデルをComfyUIの重みフォルダ `ComfyUI/models/Fun_Models/` に入れます:
|
||||
```
|
||||
📦 ComfyUI/
|
||||
├── 📂 models/
|
||||
│ └── 📂 Fun_Models/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
|
||||
│ ├── 📂 Wan2.1-Fun-V1.1-14B-InP
|
||||
│ └── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
|
||||
```
|
||||
|
||||
**独自のpythonファイルまたはUIインターフェースを実行**:
|
||||
```
|
||||
📦 models/
|
||||
├── 📂 Diffusion_Transformer/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
|
||||
│ ├── 📂 Wan2.1-Fun-V1.1-14B-InP
|
||||
│ └── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
|
||||
├── 📂 Personalized_Model/
|
||||
│ └── あなたのトレーニング済みのトランスフォーマーモデル / あなたのトレーニング済みのLoraモデル(UIロード用)
|
||||
```
|
||||
|
||||
# ビデオ結果
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-InP && Wan2.1-Fun-V1.1-1.3B-InP
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
|
||||
|
||||
Generic Control Video + Reference Image:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Reference Image
|
||||
</td>
|
||||
<td>
|
||||
Control Video
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-14B-Control
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-1.3B-Control
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</table>
|
||||
|
||||
|
||||
Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</table>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Pan Up
|
||||
</td>
|
||||
<td>
|
||||
Pan Left
|
||||
</td>
|
||||
<td>
|
||||
Pan Right
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
Pan Down
|
||||
</td>
|
||||
<td>
|
||||
Pan Up + Pan Left
|
||||
</td>
|
||||
<td>
|
||||
Pan Up + Pan Right
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B
|
||||
|
||||
解像度-1024
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
解像度-768
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
解像度-512
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B-Control
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
美しい澄んだ目と金髪の若い女性が白い服を着て体をひねり、カメラは彼女の顔に焦点を合わせています。高品質、傑作、最高品質、高解像度、超微細、夢のような。
|
||||
</td>
|
||||
<td>
|
||||
美しい澄んだ目と金髪の若い女性が白い服を着て体をひねり、カメラは彼女の顔に焦点を合わせています。高品質、傑作、最高品質、高解像度、超微細、夢のような。
|
||||
</td>
|
||||
<td>
|
||||
若いクマ。
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
# 使い方
|
||||
|
||||
<h3 id="video-gen">1. 生成</h3>
|
||||
|
||||
#### a. GPUメモリ節約方法
|
||||
Wan2.1のパラメータが非常に大きいため、GPUメモリを節約し、コンシューマー向けGPUに適応させる必要があります。各予測ファイルには`GPU_memory_mode`を提供しており、`model_cpu_offload`、`model_cpu_offload_and_qfloat8`、`sequential_cpu_offload`の中から選択できます。この方法はCogVideoX-Funの生成にも適用されます。
|
||||
|
||||
- `model_cpu_offload`: モデル全体が使用後にCPUに移動し、一部のGPUメモリを節約します。
|
||||
- `model_cpu_offload_and_qfloat8`: モデル全体が使用後にCPUに移動し、Transformerモデルに対してfloat8の量子化を行い、より多くのGPUメモリを節約します。
|
||||
- `sequential_cpu_offload`: モデルの各層が使用後にCPUに移動します。速度は遅くなりますが、大量のGPUメモリを節約します。
|
||||
|
||||
`qfloat8`はモデルの性能を部分的に低下させる可能性がありますが、より多くのGPUメモリを節約できます。十分なGPUメモリがある場合は、`model_cpu_offload`の使用をお勧めします。
|
||||
|
||||
#### b. ComfyUIを使用する
|
||||
詳細は[ComfyUI README](comfyui/README.md)をご覧ください。
|
||||
|
||||
#### c. Pythonファイルを実行する
|
||||
|
||||
##### i. 単一GPUでの推論:
|
||||
|
||||
- ステップ1: 対応する[重み](#model-zoo)をダウンロードし、`models`フォルダに配置します。
|
||||
- ステップ2: 異なる重みと予測目標に基づいて、異なるファイルを使用して予測を行います。現在、このライブラリはCogVideoX-Fun、Wan2.1、およびWan2.1-Funをサポートしています。`examples`フォルダ内のフォルダ名で区別され、異なるモデルがサポートする機能が異なりますので、状況に応じて区別してください。以下はCogVideoX-Funを例として説明します。
|
||||
- テキストからビデオ:
|
||||
- `examples/cogvideox_fun/predict_t2v.py`ファイルで`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- 次に、`examples/cogvideox_fun/predict_t2v.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos`フォルダに保存されます。
|
||||
- 画像からビデオ:
|
||||
- `examples/cogvideox_fun/predict_i2v.py`ファイルで`validation_image_start`、`validation_image_end`、`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- `validation_image_start`はビデオの開始画像、`validation_image_end`はビデオの終了画像です。
|
||||
- 次に、`examples/cogvideox_fun/predict_i2v.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos_i2v`フォルダに保存されます。
|
||||
- ビデオからビデオ:
|
||||
- `examples/cogvideox_fun/predict_v2v.py`ファイルで`validation_video`、`validation_image_end`、`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- `validation_video`はビデオ生成のための参照ビデオです。以下のデモビデオを使用して実行できます:[デモビデオ](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/play_guitar.mp4)
|
||||
- 次に、`examples/cogvideox_fun/predict_v2v.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos_v2v`フォルダに保存されます。
|
||||
- 通常の制御付きビデオ生成(Canny、Pose、Depthなど):
|
||||
- `examples/cogvideox_fun/predict_v2v_control.py`ファイルで`control_video`、`validation_image_end`、`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- `control_video`は、Canny、Pose、Depthなどの演算子で抽出された制御用ビデオです。以下のデモビデオを使用して実行できます:[デモビデオ](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/pose.mp4)
|
||||
- 次に、`examples/cogvideox_fun/predict_v2v_control.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos_v2v_control`フォルダに保存されます。
|
||||
- ステップ3: 自分でトレーニングした他のバックボーンやLoraを組み合わせたい場合は、必要に応じて`examples/{model_name}/predict_t2v.py`や`examples/{model_name}/predict_i2v.py`、`lora_path`を修正します。
|
||||
|
||||
##### ii. 複数GPUでの推論:
|
||||
多カードでの推論を行う際は、xfuserリポジトリのインストールに注意してください。xfuser==0.4.2 と yunchang==0.6.2 のインストールが推奨されます。
|
||||
```
|
||||
pip install xfuser==0.4.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
pip install yunchang==0.6.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
```
|
||||
|
||||
`ulysses_degree` と `ring_degree` の積が使用する GPU 数と一致することを確認してください。たとえば、8つのGPUを使用する場合、`ulysses_degree=2` と `ring_degree=4`、または `ulysses_degree=4` と `ring_degree=2` を設定することができます。
|
||||
|
||||
- `ulysses_degree` はヘッド(head)に分割した後の並列化を行います。
|
||||
- `ring_degree` はシーケンスに分割した後の並列化を行います。
|
||||
|
||||
`ring_degree` は `ulysses_degree` よりも通信コストが高いため、これらのパラメータを設定する際には、シーケンス長とモデルのヘッド数を考慮する必要があります。
|
||||
|
||||
8GPUでの並列推論を例に挙げます:
|
||||
|
||||
- **Wan2.1-Fun-V1.1-14B-InP** はヘッド数が40あります。この場合、`ulysses_degree` は40で割り切れる値(例:2, 4, 8など)に設定する必要があります。したがって、8GPUを使用して並列推論を行う場合、`ulysses_degree=8` と `ring_degree=1` を設定できます。
|
||||
|
||||
- **Wan2.1-Fun-V1.1-1.3B-InP** はヘッド数が12あります。この場合、`ulysses_degree` は12で割り切れる値(例:2, 4など)に設定する必要があります。したがって、8GPUを使用して並列推論を行う場合、`ulysses_degree=4` と `ring_degree=2` を設定できます。
|
||||
|
||||
パラメータの設定が完了したら、以下のコマンドで並列推論を実行してください:
|
||||
|
||||
```sh
|
||||
torchrun --nproc-per-node=8 examples/wan2.1_fun/predict_t2v.py
|
||||
```
|
||||
|
||||
#### d. UIインターフェースを使用する
|
||||
|
||||
WebUIは、テキストからビデオ、画像からビデオ、ビデオからビデオ、および通常の制御付きビデオ生成(Canny、Pose、Depthなど)をサポートします。現在、このライブラリはCogVideoX-Fun、Wan2.1、およびWan2.1-Funをサポートしており、`examples`フォルダ内のフォルダ名で区別されています。異なるモデルがサポートする機能が異なるため、状況に応じて区別してください。以下はCogVideoX-Funを例として説明します。
|
||||
|
||||
- ステップ1: 対応する[重み](#model-zoo)をダウンロードし、`models`フォルダに配置します。
|
||||
- ステップ2: `examples/cogvideox_fun/app.py`ファイルを実行し、Gradioページに入ります。
|
||||
- ステップ3: ページ上で生成モデルを選択し、`prompt`、`neg_prompt`、`guidance_scale`、`seed`などを入力し、「生成」をクリックして結果が生成されるのを待ちます。結果は`sample`フォルダに保存されます。
|
||||
|
||||
### 2. モデルのトレーニング
|
||||
完全なモデルトレーニングの流れには、データの前処理とVideo DiTのトレーニングが含まれるべきです。異なるモデルのトレーニングプロセスは類似しており、データ形式も類似しています:
|
||||
|
||||
<h4 id="data-preprocess">a. データ前処理</h4>
|
||||
|
||||
画像データを使用してLoraモデルをトレーニングする簡単なデモを提供しました。詳細は[wiki](https://github.com/aigc-apps/CogVideoX-Fun/wiki/Training-Lora)をご覧ください。
|
||||
|
||||
長いビデオのセグメンテーション、クリーニング、説明のための完全なデータ前処理リンクは、ビデオキャプションセクションの[README](cogvideox/video_caption/README.md)を参照してください。
|
||||
|
||||
テキストから画像およびビデオ生成モデルをトレーニングしたい場合。この形式でデータセットを配置する必要があります。
|
||||
|
||||
```
|
||||
📦 project/
|
||||
├── 📂 datasets/
|
||||
│ ├── 📂 internal_datasets/
|
||||
│ ├── 📂 train/
|
||||
│ │ ├── 📄 00000001.mp4
|
||||
│ │ ├── 📄 00000002.jpg
|
||||
│ │ └── 📄 .....
|
||||
│ └── 📄 json_of_internal_datasets.json
|
||||
```
|
||||
|
||||
json_of_internal_datasets.jsonは標準のJSONファイルです。json内のfile_pathは相対パスとして設定できます。以下のように:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "train/00000001.mp4",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "video"
|
||||
},
|
||||
{
|
||||
"file_path": "train/00000002.jpg",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "image"
|
||||
},
|
||||
.....
|
||||
]
|
||||
```
|
||||
|
||||
次のように絶対パスとして設定することもできます:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "/mnt/data/videos/00000001.mp4",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "video"
|
||||
},
|
||||
{
|
||||
"file_path": "/mnt/data/train/00000001.jpg",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "image"
|
||||
},
|
||||
.....
|
||||
]
|
||||
```
|
||||
|
||||
<h4 id="dit-train">b. Video DiTトレーニング </h4>
|
||||
|
||||
データ前処理時にデータ形式が相対パスの場合、```scripts/{model_name}/train.sh```を次のように設定します。
|
||||
```
|
||||
export DATASET_NAME="datasets/internal_datasets/"
|
||||
export DATASET_META_NAME="datasets/internal_datasets/json_of_internal_datasets.json"
|
||||
```
|
||||
|
||||
データ形式が絶対パスの場合、```scripts/train.sh```を次のように設定します。
|
||||
```
|
||||
export DATASET_NAME=""
|
||||
export DATASET_META_NAME="/mnt/data/json_of_internal_datasets.json"
|
||||
```
|
||||
|
||||
次に、scripts/train.shを実行します。
|
||||
```sh
|
||||
sh scripts/train.sh
|
||||
```
|
||||
いくつかのパラメータ設定の詳細について:
|
||||
Wan2.1-Funは[Readme Train](scripts/wan2.1_fun/README_TRAIN.md)と[Readme Lora](scripts/wan2.1_fun/README_TRAIN_LORA.md)を参照してください。
|
||||
Wan2.1は[Readme Train](scripts/wan2.1/README_TRAIN.md)と[Readme Lora](scripts/wan2.1/README_TRAIN_LORA.md)を参照してください。
|
||||
CogVideoX-Funは[Readme Train](scripts/cogvideox_fun/README_TRAIN.md)と[Readme Lora](scripts/cogvideox_fun/README_TRAIN_LORA.md)を参照してください。
|
||||
|
||||
# モデルの場所
|
||||
|
||||
## 1. Wan2.2-Fun
|
||||
|
||||
| 名前 | ストレージ容量 | Hugging Face | Model Scope | 説明 |
|
||||
|------|----------------|------------|-------------|------|
|
||||
| Wan2.2-Fun-A14B-InP | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-InP) | Wan2.2-Fun-14Bのテキスト・画像から動画を生成するモデルの重み。複数の解像度で学習されており、動画の最初と最後のフレームの予測をサポートしています。 |
|
||||
| Wan2.2-Fun-A14B-Control | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control) | Wan2.2-Fun-14Bの動画制御用重み。Canny、Depth、Pose、MLSDなどのさまざまな制御条件に対応しており、軌跡制御もサポートしています。512、768、1024の複数解像度での動画生成が可能で、81フレーム、16fpsで学習されています。多言語対応の予測もサポートしています。 |
|
||||
| Wan2.2-Fun-A14B-Contro-Camera | 64.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control-Camera) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control-Camera)| Wan2.2-Fun-14Bのカメラレンズ制御重み。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
| Wan2.2-VACE-Fun-A14B | 64.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.2-VACE-Fun-A14B) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.2-VACE-Fun-A14B) | VACE方式でトレーニングされたWan2.2の制御ウェイト(ベースモデルはWan2.2-T2V-A14B)。Canny、Depth、Pose、MLSD、軌道制御などの異なる制御条件をサポートします。対象を指定して動画生成が可能です。多解像度(512、768、1024)の動画予測をサポートし、81フレームで16FPSでトレーニングされています。多言語予測にも対応しています。 |
|
||||
| Wan2.2-Fun-5B-InP | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-InP) | Wan2.2-Fun-5B テキストから動画生成用の重み。121フレーム、24 FPSで学習され、先頭/末尾フレーム予測をサポート。 |
|
||||
| Wan2.2-Fun-5B-Control | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control)| Wan2.2-Fun-5B 動画制御用重み。Canny、Depth、Pose、MLSDなどの制御条件や軌道制御をサポート。121フレーム、24 FPSで学習され、多言語予測に対応。 |
|
||||
| Wan2.2-Fun-5B-Control-Camera | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control-Camera)| Wan2.2-Fun-5B カメラレンズ制御用重み。121フレーム、24 FPSで学習され、多言語予測に対応。 |
|
||||
|
||||
## 2. Wan2.2
|
||||
|
||||
| モデル名 | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|
|
||||
| Wan2.2-TI2V-5B | [🤗リンク](https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B) | [😄リンク](https://www.modelscope.cn/models/Wan-AI/Wan2.2-TI2V-5B) | 万象2.2-5B テキストから動画生成重み |
|
||||
| Wan2.2-T2V-A14B | [🤗リンク](https://huggingface.co/Wan-AI/Wan2.2-T2V-A14B) | [😄リンク](https://www.modelscope.cn/models/Wan-AI/Wan2.2-T2V-A14B) | 万象2.2-14B テキストから動画生成重み |
|
||||
| Wan2.2-I2V-A14B | [🤗リンク](https://huggingface.co/Wan-AI/Wan2.2-I2V-A14B) | [😄リンク](https://www.modelscope.cn/models/Wan-AI/Wan2.2-I2V-A14B) | 万象2.2-14B 画像から動画生成重み |
|
||||
|
||||
## 3. Wan2.1-Fun
|
||||
|
||||
V1.1:
|
||||
| 名称 | ストレージ容量 | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-V1.1-1.3B-InP | 19.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP) | Wan2.1-Fun-V1.1-1.3Bのテキスト・画像から動画生成の重み。マルチ解像度で訓練され、最初と最後の画像予測をサポートします。 |
|
||||
| Wan2.1-Fun-V1.1-14B-InP | 47.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP) | Wan2.1-Fun-V1.1-14Bのテキスト・画像から動画生成の重み。マルチ解像度で訓練され、最初と最後の画像予測をサポートします。 |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control | 19.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control)| Wan2.1-Fun-V1.1-1.3Bのビデオ制御重み。Canny、Depth、Pose、MLSDなどの異なる制御条件に対応し、参照画像+制御条件を使用した制御や軌跡制御をサポートします。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control)| Wan2.1-Fun-V1.1-14Bのビデオ制御重み。Canny、Depth、Pose、MLSDなどの異なる制御条件に対応し、参照画像+制御条件を使用した制御や軌跡制御をサポートします。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control-Camera | 19.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control-Camera) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control-Camera)| Wan2.1-Fun-V1.1-1.3Bのカメラレンズ制御重み。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
| Wan2.1-Fun-V1.1-14B-Control-Camera | 47.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control-Camera) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control-Camera)| Wan2.1-Fun-V1.1-14Bのカメラレンズ制御重み。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
|
||||
|
||||
V1.0:
|
||||
| 名称 | ストレージ容量 | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-InP) | Wan2.1-Fun-1.3Bのテキスト・画像から動画生成する重み。マルチ解像度で学習され、開始・終了画像予測をサポート。 |
|
||||
| Wan2.1-Fun-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP) | Wan2.1-Fun-14Bのテキスト・画像から動画生成する重み。マルチ解像度で学習され、開始・終了画像予測をサポート。 |
|
||||
| Wan2.1-Fun-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-Control) | Wan2.1-Fun-1.3Bのビデオ制御ウェイト。Canny、Depth、Pose、MLSDなどの異なる制御条件をサポートし、トラジェクトリ制御も利用可能。512、768、1024のマルチ解像度でのビデオ予測をサポートし、81フレーム(1秒間に16フレーム)でトレーニング済みで、多言語予測にも対応しています。 |
|
||||
| Wan2.1-Fun-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-Control) | Wan2.1-Fun-14Bのビデオ制御ウェイト。Canny、Depth、Pose、MLSDなどの異なる制御条件をサポートし、トラジェクトリ制御も利用可能。512、768、1024のマルチ解像度でのビデオ予測をサポートし、81フレーム(1秒間に16フレーム)でトレーニング済みで、多言語予測にも対応しています。 |
|
||||
|
||||
## 4. Wan2.1
|
||||
|
||||
| 名称 | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|
|
||||
| Wan2.1-T2V-1.3B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-1.3B) | 万象2.1-1.3Bのテキストから動画生成する重み |
|
||||
| Wan2.1-T2V-14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-14B) | 万象2.1-14Bのテキストから動画生成する重み |
|
||||
| Wan2.1-I2V-14B-480P | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-480P) | 万象2.1-14B-480Pの画像から動画生成する重み |
|
||||
| Wan2.1-I2V-14B-720P| [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | 万象2.1-14B-720Pの画像から動画生成する重み |
|
||||
|
||||
## 5. FantasyTalking
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-I2V-14B-720P | - | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | 万象2.1-14B-720P 画像→動画モデルの重み |
|
||||
| Wav2Vec | - | [🤗Link](https://huggingface.co/facebook/wav2vec2-base-960h) | [😄Link](https://modelscope.cn/models/AI-ModelScope/wav2vec2-base-960h) | Wav2Vecモデル。Wan2.1-I2V-14B-720Pフォルダ内に配置し、`audio_encoder` という名前に変更してください |
|
||||
| FantasyTalking model | - | [🤗Link](https://huggingface.co/acvlab/FantasyTalking/) | [😄Link](https://www.modelscope.cn/models/amap_cvlab/FantasyTalking/) | 公式Audio Condition重み |
|
||||
|
||||
## 6. Qwen-Image
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image | [🤗Link](https://huggingface.co/Qwen/Qwen-Image) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image) | Qwen-Image 公式重み |
|
||||
| Qwen-Image-Edit | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit) | Qwen-Image-Edit 公式重み |
|
||||
| Qwen-Image-Edit-2509 | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit-2509) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509) | Qwen-Image-Edit-2509 公式重み |
|
||||
|
||||
## 7. Qwen-Image-Fun
|
||||
|
||||
| 名前 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image-2512-Fun-Controlnet-Union | - | [🤗リンク](https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union) | [😄リンク](https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union) | Qwen-Image-2512のControlNet重み。Canny、Depth、Pose、MLSD、Scribbleなど、複数の制御条件をサポートします。 |
|
||||
|
||||
## 8. Z-Image
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image | [🤗リンク](https://huggingface.co/Tongyi-MAI/Z-Image) | [😄リンク](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image) | Z-Imageの公式重み |
|
||||
| Z-Image-Turbo | [🤗リンク](https://huggingface.co/Tongyi-MAI/Z-Image-Turbo) | [😄リンク](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo) | Z-Image-Turboの公式重み |
|
||||
|
||||
## 9. Z-Image-Fun
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image-Fun-Controlnet-Union-2.1 | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1) | Z-ImageのControlNet重み、Canny、Depth、Pose、MLSD、ScribbleおよびGrayなど複数の制御条件に対応。 |
|
||||
| Z-Image-Fun-Lora-Distill | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill) | これはZ-Image用の蒸留LoRAで、ステップ数とCFGの両方を蒸留します。このモデルはCFGを必要とせず、推論には8ステップを使用します。 |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union | - | [🤗リンク](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union) | [😄リンク](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union) | Z-Image-Turbo用のControlNet重み。Canny、Depth、Pose、MLSDなど複数の制御条件をサポート。 |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union-2.1 | - | [🤗リンク](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | [😄リンク](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | Z-Image-TurboのControlNet重み。第1版と比較して、より多くの層に追加され、より長時間トレーニングされています。Canny、Depth、Pose、MLSDなど、複数の制御条件をサポートしています。 |
|
||||
|
||||
## 10. Flux
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| FLUX.1-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.1-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev)| FLUX.1-dev 公式重み |
|
||||
| FLUX.2-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.2-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev) | FLUX.2-dev 公式重み |
|
||||
|
||||
## 11. Flux-Fun
|
||||
|
||||
| 名前 | ストレージ | Hugging Face | ModelScope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Flux.2-dev-Fun-Controlnet-Union | - | [🤗リンク](https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union) | [😄リンク](https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union) | Flux.2-dev 用の ControlNet 重みで、Canny、Depth、Pose、MLSD など様々な制御条件をサポートします。 |
|
||||
|
||||
## 12. HunyuanVideo
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| HunyuanVideo | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo) | - | HunyuanVideo-diffusers 公式重み |
|
||||
| HunyuanVideo-I2V | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo-I2V) | - | HunyuanVideo-I2V-diffusers 公式重み |
|
||||
|
||||
## 13. CogVideoX-Fun
|
||||
|
||||
V1.5:
|
||||
|
||||
| 名称 | ストレージスペース | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.5-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-5b-InP) | 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024)でビデオを予測できます。85フレーム、8フレーム/秒でトレーニングされています。 |
|
||||
| CogVideoX-Fun-V1.5-Reward-LoRAs | - | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs) | 公式の報酬逆伝播技術モデルで、CogVideoX-Fun-V1.5が生成するビデオを最適化し、人間の嗜好によりよく合うようにする。 |
|
||||
|
||||
V1.1:
|
||||
|
||||
| 名称 | ストレージスペース | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.1-2b-InP | 13.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-InP) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-InP) | 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。参照画像にノイズが追加され、V1.0と比較して動きの幅が広がっています。 |
|
||||
| CogVideoX-Fun-V1.1-5b-InP | 20.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP) | 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。参照画像にノイズが追加され、V1.0と比較して動きの幅が広がっています。 |
|
||||
| CogVideoX-Fun-V1.1-2b-Pose | 13.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Pose) | 公式のポーズコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。|
|
||||
| CogVideoX-Fun-V1.1-2b-Control | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Control) | 公式のコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。Canny、Depth、Pose、MLSDなどのさまざまなコントロール条件をサポートします。|
|
||||
| CogVideoX-Fun-V1.1-5b-Pose | 20.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Pose) | 公式のポーズコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。|
|
||||
| CogVideoX-Fun-V1.1-5b-Control | 20.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Control) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Control) | 公式のコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。Canny、Depth、Pose、MLSDなどのさまざまなコントロール条件をサポートします。|
|
||||
| CogVideoX-Fun-V1.1-Reward-LoRAs | - | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs) | 公式の報酬逆伝播技術モデルで、CogVideoX-Fun-V1.1が生成するビデオを最適化し、人間の嗜好によりよく合うようにする。 |
|
||||
|
||||
<details>
|
||||
<summary>(Obsolete) V1.0:</summary>
|
||||
|
||||
| 名称 | ストレージスペース | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP | 13.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-2b-InP) | 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。 |
|
||||
| CogVideoX-Fun-5b-InP | 20.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP)| [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-5b-InP)| 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。|
|
||||
</details>
|
||||
|
||||
# 参考文献
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
|
||||
- Wan2.1: https://github.com/Wan-Video/Wan2.1/
|
||||
- Wan2.2: https://github.com/Wan-Video/Wan2.2/
|
||||
- Diffusers: https://github.com/huggingface/diffusers
|
||||
- Qwen-Image: https://github.com/QwenLM/Qwen-Image
|
||||
- Self-Forcing: https://github.com/guandeh17/Self-Forcing
|
||||
- Flux: https://github.com/black-forest-labs/flux
|
||||
- Flux2: https://github.com/black-forest-labs/flux2
|
||||
- HunyuanVideo: https://github.com/Tencent-Hunyuan/HunyuanVideo
|
||||
- ComfyUI-KJNodes: https://github.com/kijai/ComfyUI-KJNodes
|
||||
- ComfyUI-EasyAnimateWrapper: https://github.com/kijai/ComfyUI-EasyAnimateWrapper
|
||||
- ComfyUI-CameraCtrl-Wrapper: https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper
|
||||
- CameraCtrl: https://github.com/hehao13/CameraCtrl
|
||||
|
||||
# ライセンス
|
||||
このプロジェクトは[Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE)の下でライセンスされています。
|
||||
|
||||
CogVideoX-2Bモデル(対応するTransformersモジュール、VAEモジュールを含む)は、[Apache 2.0ライセンス](LICENSE)の下でリリースされています。
|
||||
|
||||
CogVideoX-5Bモデル(Transformersモジュール)は、[CogVideoXライセンス](https://huggingface.co/THUDM/CogVideoX-5b/blob/main/LICENSE)の下でリリースされています。
|
||||
@@ -1,60 +1,45 @@
|
||||
# VideoX-Fun
|
||||
# CogVideoX-Fun
|
||||
|
||||
😊 Welcome!
|
||||
|
||||
CogVideoX-Fun:
|
||||
[](https://huggingface.co/spaces/alibaba-pai/CogVideoX-Fun-5b)
|
||||
|
||||
Wan-Fun:
|
||||
[](https://huggingface.co/spaces/alibaba-pai/Wan2.1-Fun-1.3B-InP)
|
||||
|
||||
[English](./README.md) | 简体中文 | [日本語](./README_ja-JP.md)
|
||||
[English](./README.md) | 简体中文
|
||||
|
||||
# 目录
|
||||
- [目录](#目录)
|
||||
- [简介](#简介)
|
||||
- [快速启动](#快速启动)
|
||||
- [视频作品](#视频作品)
|
||||
- [如何使用](#如何使用)
|
||||
- [模型地址](#模型地址)
|
||||
- [未来计划](#未来计划)
|
||||
- [参考文献](#参考文献)
|
||||
- [许可证](#许可证)
|
||||
|
||||
# 简介
|
||||
VideoX-Fun是一个视频生成的pipeline,可用于生成AI图片与视频、训练Diffusion Transformer的基线模型与Lora模型,我们支持从已经训练好的基线模型直接进行预测,生成不同分辨率,不同秒数、不同FPS的视频,也支持用户训练自己的基线模型与Lora模型,进行一定的风格变换。
|
||||
CogVideoX-Fun是一个基于CogVideoX结构修改后的的pipeline,是一个生成条件更自由的CogVideoX,可用于生成AI图片与视频、训练Diffusion Transformer的基线模型与Lora模型,我们支持从已经训练好的CogVideoX-Fun模型直接进行预测,生成不同分辨率,6秒左右、fps8的视频(1 ~ 49帧),也支持用户训练自己的基线模型与Lora模型,进行一定的风格变换。
|
||||
|
||||
我们会逐渐支持从不同平台快速启动,请参阅 [快速启动](#快速启动)。
|
||||
|
||||
新特性:
|
||||
- 更新支持Wan2.2系列模型、Wan-VACE控制模型、支持Fantasy Talking数字人模型、Qwen-Image和Flux图片生成模型等。[2025.10.16]。
|
||||
- 更新Wan2.1-Fun-V1.1版本:支持14B与1.3B模型Control+参考图模型,支持镜头控制,另外Inpaint模型重新训练,性能更佳。[2025.04.25]
|
||||
- 更新Wan2.1-Fun-V1.0版本:支持14B与1.3B模型的I2V和Control模型,支持首尾图预测。[2025.03.26]
|
||||
- 更新CogVideoX-Fun-V1.5版本:上传I2V模型与相关训练预测代码。[2024.12.16]
|
||||
- 奖励Lora支持:通过奖励反向传播技术训练Lora,以优化生成的视频,使其更好地与人类偏好保持一致,[更多信息](scripts/README_TRAIN_REWARD.md)。新版本的控制模型,支持不同的控制条件,如Canny、Depth、Pose、MLSD等。[2024.11.21]
|
||||
- diffusers支持:CogVideoX-Fun Control现在在diffusers中得到了支持。感谢 [a-r-r-o-w](https://github.com/a-r-r-o-w)在这个 [PR](https://github.com/huggingface/diffusers/pull/9671)中贡献了支持。查看[文档](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cogvideox)以了解更多信息。[2024.10.16]
|
||||
- 更新CogVideoX-Fun-V1.1版本:重新训练i2v模型,添加Noise,使得视频的运动幅度更大。上传控制模型训练代码与Control模型。[2024.09.29]
|
||||
- 更新CogVideoX-Fun-V1.0版本:创建代码!现在支持 Windows 和 Linux。支持2b与5b最大256x256x49到1024x1024x49的任意分辨率的视频生成。[2024.09.18]
|
||||
- 创建代码!现在支持 Windows 和 Linux。支持最大256x256x49到1024x1024x49的任意分辨率的视频生成。[ 2024.09.09 ]
|
||||
|
||||
功能概览:
|
||||
- [数据预处理](#data-preprocess)
|
||||
- [训练DiT](#dit-train)
|
||||
- [模型生成](#video-gen)
|
||||
|
||||
这些是我们的生成结果 [GALLERY](scripts/Result_Gallery.md) (点击下方的图片可查看视频):
|
||||
|
||||
我们的ui界面如下:
|
||||

|
||||
|
||||
# 快速启动
|
||||
### 1. 云使用: AliyunDSW/Docker
|
||||
#### a. 通过阿里云 DSW
|
||||
DSW 有免费 GPU 时间,用户可申请一次,申请后3个月内有效。
|
||||
|
||||
阿里云在[Freetier](https://free.aliyun.com/?product=9602825&crowd=enterprise&spm=5176.28055625.J_5831864660.1.e939154aRgha4e&scm=20140722.M_9974135.P_110.MO_1806-ID_9974135-MID_9974135-CID_30683-ST_8512-V_1)提供免费GPU时间,获取并在阿里云PAI-DSW中使用,5分钟内即可启动CogVideoX-Fun。
|
||||
|
||||
[](https://gallery.pai-ml.com/#/preview/deepLearning/cv/cogvideox_fun)
|
||||
正在路上
|
||||
|
||||
#### b. 通过ComfyUI
|
||||
我们的ComfyUI界面如下,具体查看[ComfyUI README](comfyui/README.md)。
|
||||

|
||||

|
||||
|
||||
#### c. 通过docker
|
||||
使用docker的情况下,请保证机器中已经正确安装显卡驱动与CUDA环境,然后以此执行以下命令:
|
||||
@@ -67,28 +52,25 @@ docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cud
|
||||
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# clone code
|
||||
git clone https://github.com/aigc-apps/VideoX-Fun.git
|
||||
git clone https://github.com/aigc-apps/CogVideoX-Fun.git
|
||||
|
||||
# enter VideoX-Fun's dir
|
||||
cd VideoX-Fun
|
||||
# enter CogVideoX-Fun's dir
|
||||
cd CogVideoX-Fun
|
||||
|
||||
# download weights
|
||||
mkdir models/Diffusion_Transformer
|
||||
mkdir models/Personalized_Model
|
||||
|
||||
# Please use the hugginface link or modelscope link to download the model.
|
||||
# CogVideoX-Fun
|
||||
# https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP
|
||||
# https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP
|
||||
wget https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz -O models/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz
|
||||
|
||||
# Wan
|
||||
# https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP
|
||||
# https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP
|
||||
cd models/Diffusion_Transformer/
|
||||
tar -xvf CogVideoX-Fun-2b-InP.tar.gz
|
||||
cd ../../
|
||||
```
|
||||
|
||||
### 2. 本地安装: 环境检查/下载/安装
|
||||
#### a. 环境检查
|
||||
我们已验证该库可在以下环境中执行:
|
||||
我们已验证CogVideoX-Fun可在以下环境中执行:
|
||||
|
||||
Windows 的详细信息:
|
||||
- 操作系统 Windows 10
|
||||
@@ -111,353 +93,35 @@ Linux 的详细信息:
|
||||
#### b. 权重放置
|
||||
我们最好将[权重](#model-zoo)按照指定路径进行放置:
|
||||
|
||||
**通过comfyui**:
|
||||
将模型放入Comfyui的权重文件夹`ComfyUI/models/Fun_Models/`:
|
||||
```
|
||||
📦 ComfyUI/
|
||||
├── 📂 models/
|
||||
│ └── 📂 Fun_Models/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
|
||||
│ ├── 📂 Wan2.1-Fun-V1.1-14B-InP
|
||||
│ └── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
|
||||
```
|
||||
|
||||
**运行自身的python文件或ui界面**:
|
||||
```
|
||||
📦 models/
|
||||
├── 📂 Diffusion_Transformer/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
|
||||
│ ├── 📂 Wan2.1-Fun-V1.1-14B-InP
|
||||
│ └── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
|
||||
│ └── 📂 CogVideoX-Fun-2b-InP/
|
||||
├── 📂 Personalized_Model/
|
||||
│ └── your trained trainformer model / your trained lora model (for UI load)
|
||||
```
|
||||
|
||||
# 视频作品
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-InP && Wan2.1-Fun-V1.1-1.3B-InP
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
|
||||
|
||||
Generic Control Video + Reference Image:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Reference Image
|
||||
</td>
|
||||
<td>
|
||||
Control Video
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-14B-Control
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-1.3B-Control
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</table>
|
||||
|
||||
|
||||
Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</table>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Pan Up
|
||||
</td>
|
||||
<td>
|
||||
Pan Left
|
||||
</td>
|
||||
<td>
|
||||
Pan Right
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
Pan Down
|
||||
</td>
|
||||
<td>
|
||||
Pan Up + Pan Left
|
||||
</td>
|
||||
<td>
|
||||
Pan Up + Pan Right
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B
|
||||
|
||||
Resolution-1024
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
Resolution-768
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
Resolution-512
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B-Control
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
A young woman with beautiful clear eyes and blonde hair, wearing white clothes and twisting her body, with the camera focused on her face. High quality, masterpiece, best quality, high resolution, ultra-fine, dreamlike.
|
||||
</td>
|
||||
<td>
|
||||
A young woman with beautiful clear eyes and blonde hair, wearing white clothes and twisting her body, with the camera focused on her face. High quality, masterpiece, best quality, high resolution, ultra-fine, dreamlike.
|
||||
</td>
|
||||
<td>
|
||||
A young bear.
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
# 如何使用
|
||||
|
||||
<h3 id="video-gen">1. 生成 </h3>
|
||||
|
||||
#### a、显存节省方案
|
||||
由于Wan2.1的参数非常大,我们需要考虑显存节省方案,以节省显存适应消费级显卡。我们给每个预测文件都提供了GPU_memory_mode,可以在model_cpu_offload,model_cpu_offload_and_qfloat8,sequential_cpu_offload中进行选择。该方案同样适用于CogVideoX-Fun的生成。
|
||||
|
||||
- model_cpu_offload代表整个模型在使用后会进入cpu,可以节省部分显存。
|
||||
- model_cpu_offload_and_qfloat8代表整个模型在使用后会进入cpu,并且对transformer模型进行了float8的量化,可以节省更多的显存。
|
||||
- sequential_cpu_offload代表模型的每一层在使用后会进入cpu,速度较慢,节省大量显存。
|
||||
|
||||
qfloat8会部分降低模型的性能,但可以节省更多的显存。如果显存足够,推荐使用model_cpu_offload。
|
||||
|
||||
#### b、通过comfyui
|
||||
具体查看[ComfyUI README](comfyui/README.md)。
|
||||
|
||||
#### c、运行python文件
|
||||
|
||||
##### i、单卡运行:
|
||||
|
||||
#### a. 视频生成
|
||||
##### i、运行python文件
|
||||
- 步骤1:下载对应[权重](#model-zoo)放入models文件夹。
|
||||
- 步骤2:根据不同的权重与预测目标使用不同的文件进行预测。当前该库支持CogVideoX-Fun、Wan2.1和Wan2.1-Fun,在examples文件夹下用文件夹名以区分,不同模型支持的功能不同,请视具体情况予以区分。以CogVideoX-Fun为例。
|
||||
- 文生视频:
|
||||
- 使用examples/cogvideox_fun/predict_t2v.py文件中修改prompt、neg_prompt、guidance_scale和seed。
|
||||
- 而后运行examples/cogvideox_fun/predict_t2v.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos文件夹中。
|
||||
- 图生视频:
|
||||
- 使用examples/cogvideox_fun/predict_i2v.py文件中修改validation_image_start、validation_image_end、prompt、neg_prompt、guidance_scale和seed。
|
||||
- validation_image_start是视频的开始图片,validation_image_end是视频的结尾图片。
|
||||
- 而后运行examples/cogvideox_fun/predict_i2v.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos_i2v文件夹中。
|
||||
- 视频生视频:
|
||||
- 使用examples/cogvideox_fun/predict_v2v.py文件中修改validation_video、validation_image_end、prompt、neg_prompt、guidance_scale和seed。
|
||||
- validation_video是视频生视频的参考视频。您可以使用以下视频运行演示:[演示视频](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/play_guitar.mp4)
|
||||
- 而后运行examples/cogvideox_fun/predict_v2v.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos_v2v文件夹中。
|
||||
- 普通控制生视频(Canny、Pose、Depth等):
|
||||
- 使用examples/cogvideox_fun/predict_v2v_control.py文件中修改control_video、validation_image_end、prompt、neg_prompt、guidance_scale和seed。
|
||||
- control_video是控制生视频的控制视频,是使用Canny、Pose、Depth等算子提取后的视频。您可以使用以下视频运行演示:[演示视频](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/pose.mp4)
|
||||
- 而后运行examples/cogvideox_fun/predict_v2v_control.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos_v2v_control文件夹中。
|
||||
- 步骤3:如果想结合自己训练的其他backbone与Lora,则看情况修改examples/{model_name}/predict_t2v.py中的examples/{model_name}/predict_i2v.py和lora_path。
|
||||
|
||||
##### ii、多卡运行:
|
||||
在使用多卡预测时请注意安装xfuser仓库,推荐安装xfuser==0.4.2和yunchang==0.6.2。
|
||||
```
|
||||
pip install xfuser==0.4.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
pip install yunchang==0.6.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
```
|
||||
|
||||
请确保ulysses_degree和ring_degree的乘积等于使用的GPU数量。例如,如果您使用8个GPU,则可以设置ulysses_degree=2和ring_degree=4,也可以设置ulysses_degree=4和ring_degree=2。
|
||||
|
||||
ulysses_degree是在head进行切分后并行生成,ring_degree是在sequence上进行切分后并行生成。ring_degree相比ulysses_degree有更大的通信成本,在设置参数时需要结合序列长度和模型的head数进行设置。
|
||||
|
||||
以8卡并行预测为例。
|
||||
- 以Wan2.1-Fun-V1.1-14B-InP为例,其head数为40,ulysses_degree需要设置为其可以整除的数如2、4、8等。因此在使用8卡并行预测时,可以设置ulysses_degree=8和ring_degree=1.
|
||||
- 以Wan2.1-Fun-V1.1-1.3B-InP为例,其head数为12,ulysses_degree需要设置为其可以整除的数如2、4等。因此在使用8卡并行预测时,可以设置ulysses_degree=4和ring_degree=2.
|
||||
|
||||
设置完成后,使用如下指令进行并行预测:
|
||||
```sh
|
||||
torchrun --nproc-per-node=8 examples/wan2.1_fun/predict_t2v.py
|
||||
```
|
||||
|
||||
#### d、通过ui界面
|
||||
|
||||
webui支持文生视频、图生视频、视频生视频和普通控制生视频(Canny、Pose、Depth等)。当前该库支持CogVideoX-Fun、Wan2.1和Wan2.1-Fun,在examples文件夹下用文件夹名以区分,不同模型支持的功能不同,请视具体情况予以区分。以CogVideoX-Fun为例。
|
||||
- 步骤2:在predict_t2v.py文件中修改prompt、neg_prompt、guidance_scale和seed。
|
||||
- 步骤3:运行predict_t2v.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos-t2v文件夹中。
|
||||
- 步骤4:如果想结合自己训练的其他backbone与Lora,则看情况修改predict_t2v.py中的predict_t2v.py和lora_path。
|
||||
|
||||
##### ii、通过ui界面
|
||||
- 步骤1:下载对应[权重](#model-zoo)放入models文件夹。
|
||||
- 步骤2:运行examples/cogvideox_fun/app.py文件,进入gradio页面。
|
||||
- 步骤2:运行app.py文件,进入gradio页面。
|
||||
- 步骤3:根据页面选择生成模型,填入prompt、neg_prompt、guidance_scale和seed等,点击生成,等待生成结果,结果保存在sample文件夹中。
|
||||
|
||||
##### iii、通过comfyui
|
||||
具体查看[ComfyUI README](comfyui/README.md)。
|
||||
|
||||
### 2. 模型训练
|
||||
一个完整的模型训练链路应该包括数据预处理和Video DiT训练。不同模型的训练流程类似,数据格式也类似:
|
||||
一个完整的CogVideoX-Fun训练链路应该包括数据预处理和Video DiT训练。
|
||||
|
||||
<h4 id="data-preprocess">a.数据预处理</h4>
|
||||
我们给出了一个简单的demo通过图片数据训练lora模型,详情可以查看[wiki](https://github.com/aigc-apps/CogVideoX-Fun/wiki/Training-Lora)。
|
||||
@@ -511,10 +175,14 @@ json_of_internal_datasets.json是一个标准的json文件。json中的file_path
|
||||
```
|
||||
<h4 id="dit-train">b. Video DiT训练 </h4>
|
||||
|
||||
如果数据预处理时,数据的格式为相对路径,则进入scripts/{model_name}/train.sh进行如下设置。
|
||||
如果数据预处理时,数据的格式为相对路径,则进入scripts/train.sh进行如下设置。
|
||||
```
|
||||
export DATASET_NAME="datasets/internal_datasets/"
|
||||
export DATASET_META_NAME="datasets/internal_datasets/json_of_internal_datasets.json"
|
||||
|
||||
...
|
||||
|
||||
train_data_format="normal"
|
||||
```
|
||||
|
||||
如果数据的格式为绝对路径,则进入scripts/train.sh进行如下设置。
|
||||
@@ -528,170 +196,21 @@ export DATASET_META_NAME="/mnt/data/json_of_internal_datasets.json"
|
||||
sh scripts/train.sh
|
||||
```
|
||||
|
||||
关于一些参数的设置细节:
|
||||
Wan2.1-Fun可以查看[Readme Train](scripts/wan2.1_fun/README_TRAIN.md)与[Readme Lora](scripts/wan2.1_fun/README_TRAIN_LORA.md)。
|
||||
Wan2.1可以查看[Readme Train](scripts/wan2.1/README_TRAIN.md)与[Readme Lora](scripts/wan2.1/README_TRAIN_LORA.md)。
|
||||
CogVideoX-Fun可以查看[Readme Train](scripts/cogvideox_fun/README_TRAIN.md)与[Readme Lora](scripts/cogvideox_fun/README_TRAIN_LORA.md)。
|
||||
|
||||
关于一些参数的设置细节,可以查看[Readme Train](scripts/README_TRAIN.md)与[Readme Lora](scripts/README_TRAIN_LORA.md)
|
||||
|
||||
# 模型地址
|
||||
## 1.Wan2.2-Fun
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
| 名称 | 存储空间 | 下载地址 | Hugging Face | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.2-Fun-A14B-InP | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-InP) | Wan2.2-Fun-14B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.2-Fun-A14B-Control | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control)| Wan2.2-Fun-14B视频控制权重,支持不同的控制条件,如Canny、Depth、Pose、MLSD等,同时支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.2-Fun-A14B-Control-Camera | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control-Camera)| Wan2.2-Fun-14B相机镜头控制权重。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.2-VACE-Fun-A14B | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-VACE-Fun-A14B) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-VACE-Fun-A14B)| 以VACE方案训练的Wan2.2控制权重,基础模型为Wan2.2-T2V-A14B,支持不同的控制条件,如Canny、Depth、Pose、MLSD、轨迹控制等。支持通过主体指定生视频。支持多分辨率(512,768,1024)的视频预测,支持多分辨率(512,768,1024)的视频预测,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.2-Fun-5B-InP | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-InP) | Wan2.2-Fun-5B文图生视频权重,以121帧、每秒24帧进行训练支持首尾图预测。 |
|
||||
| Wan2.2-Fun-5B-Control | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control)| Wan2.2-Fun-5B视频控制权重,支持不同的控制条件,如Canny、Depth、Pose、MLSD等,同时支持使用轨迹控制。以121帧、每秒24帧进行训练,支持多语言预测 |
|
||||
| Wan2.2-Fun-5B-Control-Camera | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control-Camera)| Wan2.2-Fun-5B相机镜头控制权重。以121帧、每秒24帧进行训练,支持多语言预测 |
|
||||
| CogVideoX-Fun-2b-InP.tar.gz | 解压前 9.69 GB / 解压后 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP)| 官方的图生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以144帧、每秒24帧进行训练 |
|
||||
|
||||
## 2. Wan2.2
|
||||
|
||||
| 名称 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|
|
||||
| Wan2.2-TI2V-5B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-TI2V-5B) | 万象2.2-5B文生视频权重 |
|
||||
| Wan2.2-T2V-A14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-T2V-A14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-T2V-A14B) | 万象2.2-14B文生视频权重 |
|
||||
| Wan2.2-I2V-A14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-I2V-A14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-I2V-A14B) | 万象2.2-14B图生视频权重 |
|
||||
|
||||
## 3. Wan2.1-Fun
|
||||
|
||||
V1.1:
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-V1.1-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP) | Wan2.1-Fun-V1.1-1.3B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.1-Fun-V1.1-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP) | Wan2.1-Fun-V1.1-14B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control)| Wan2.1-Fun-V1.1-1.3B视频控制权重支持不同的控制条件,如Canny、Depth、Pose、MLSD等,支持参考图 + 控制条件进行控制,支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control)| Wan2.1-Fun-V1.1-14B视视频控制权重支持不同的控制条件,如Canny、Depth、Pose、MLSD等,支持参考图 + 控制条件进行控制,支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control-Camera | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control-Camera)| Wan2.1-Fun-V1.1-1.3B相机镜头控制权重。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.1-Fun-V1.1-14B-Control-Camera | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control-Camera)| Wan2.1-Fun-V1.1-14B相机镜头控制权重。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
|
||||
V1.0:
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-InP) | Wan2.1-Fun-1.3B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.1-Fun-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP) | Wan2.1-Fun-14B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.1-Fun-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-Control)| Wan2.1-Fun-1.3B视频控制权重,支持不同的控制条件,如Canny、Depth、Pose、MLSD等,同时支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.1-Fun-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-Control)| Wan2.1-Fun-14B视频控制权重,支持不同的控制条件,如Canny、Depth、Pose、MLSD等,同时支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
|
||||
## 4. Wan2.1
|
||||
|
||||
| 名称 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|
|
||||
| Wan2.1-T2V-1.3B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-1.3B) | 万象2.1-1.3B文生视频权重 |
|
||||
| Wan2.1-T2V-14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-14B) | 万象2.1-14B文生视频权重 |
|
||||
| Wan2.1-I2V-14B-480P | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-480P) | 万象2.1-14B-480P图生视频权重 |
|
||||
| Wan2.1-I2V-14B-720P| [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | 万象2.1-14B-720P图生视频权重 |
|
||||
|
||||
## 5. FantasyTalking
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-I2V-14B-720P | - | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | 万象2.1-14B-720P图生视频权重 |
|
||||
| Wav2Vec | - | [🤗Link](https://huggingface.co/facebook/wav2vec2-base-960h) | [😄Link](https://modelscope.cn/models/AI-ModelScope/wav2vec2-base-960h) | Wav2Vec模型,请放在Wan2.1-I2V-14B-720P文件夹下,命名为audio_encoder |
|
||||
| FantasyTalking model | - | [🤗Link](https://huggingface.co/acvlab/FantasyTalking/) | [😄Link](https://www.modelscope.cn/models/amap_cvlab/FantasyTalking/) | 官方Audio Condition的权重。 |
|
||||
|
||||
## 6. Qwen-Image
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image | [🤗Link](https://huggingface.co/Qwen/Qwen-Image) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image) | Qwen-Image官方权重 |
|
||||
| Qwen-Image-Edit | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit) | Qwen-Image-Edit官方权重 |
|
||||
| Qwen-Image-Edit-2509 | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit-2509) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509) | Qwen-Image-Edit-2509官方权重 |
|
||||
|
||||
## 7. Qwen-Image-Fun
|
||||
|
||||
| 名称 | 存储 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image-2512-Fun-Controlnet-Union | - | [🤗链接](https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union) | [😄链接](https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union) | Qwen-Image-2512的ControlNet权重,支持多种控制条件,如Canny、Depth、Pose、MLSD、Scribble等。 |
|
||||
|
||||
## 8. Z-Image
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image | [🤗Link](https://huggingface.co/Tongyi-MAI/Z-Image) | [😄Link](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image) | Z-Image官方权重 |
|
||||
| Z-Image-Turbo | [🤗Link](https://huggingface.co/Tongyi-MAI/Z-Image-Turbo) | [😄Link](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo) | Z-Image-Turbo官方权重 |
|
||||
|
||||
## 9. Z-Image-Fun
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image-Fun-Controlnet-Union-2.1 | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1) | Z-Image 的 ControlNet 权重,支持 Canny、Depth、Pose、MLSD、Scribble和Gray 等多种控制条件。 |
|
||||
| Z-Image-Fun-Lora-Distill | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill) | 这是Z-Image的蒸馏LoRA,同时蒸馏了步数和CFG。该模型不需要CFG,推理仅使用8步。 |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union | - | [🤗链接](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union) | [😄链接](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union) | Z-Image-Turbo 的 ControlNet 权重,支持 Canny、Depth、Pose、MLSD 等多种控制条件。 |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union-2.1 | - | [🤗链接](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | [😄链接](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | Z-Image-Turbo 的 ControlNet 权重,相比第一版在更多层进行添加,也训练了更长时间,支持 Canny、Depth、Pose、MLSD 等多种控制条件。 |
|
||||
|
||||
## 10. Flux
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| FLUX.1-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.1-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev) | FLUX.1-dev官方权重 |
|
||||
| FLUX.2-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.2-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev) | FLUX.2-dev官方权重 |
|
||||
|
||||
## 11. Flux-Fun
|
||||
|
||||
| 名称 | 存储 | Hugging Face | 魔搭社区(ModelScope) | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Flux.2-dev-Fun-Controlnet-Union | - | [🤗链接](https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union) | [😄链接](https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union) | Flux.2-dev 的 ControlNet 权重,支持 Canny、Depth、Pose、MLSD 等多种控制条件。 |
|
||||
|
||||
## 12. HunyuanVideo
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| HunyuanVideo | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo) | - | HunyuanVideo-diffusers权重 |
|
||||
| HunyuanVideo-I2V | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo-I2V) | - | HunyuanVideo-I2V-diffusers权重 |
|
||||
|
||||
## 13. CogVideoX-Fun
|
||||
|
||||
V1.5:
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.5-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-5b-InP) | 官方的图生视频权重。支持多分辨率(512,768,1024)的视频预测,以85帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.5-Reward-LoRAs | - | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs) | 官方的奖励反向传播技术模型,优化CogVideoX-Fun-V1.5生成的视频,使其更好地符合人类偏好。 |
|
||||
|
||||
|
||||
V1.1:
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.1-2b-InP | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-InP) | 官方的图生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.1-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP) | 官方的图生视频权重。添加了Noise,运动幅度相比于V1.0更大。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.1-2b-Pose | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Pose) | 官方的姿态控制生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.1-2b-Control | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Control) | 官方的控制生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练。支持不同的控制条件,如Canny、Depth、Pose、MLSD等 |
|
||||
| CogVideoX-Fun-V1.1-5b-Pose | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Pose) | 官方的姿态控制生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.1-5b-Control | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Control) | 官方的控制生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练。支持不同的控制条件,如Canny、Depth、Pose、MLSD等 |
|
||||
| CogVideoX-Fun-V1.1-Reward-LoRAs | - | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-Reward-LoRAs) | 官方的奖励反向传播技术模型,优化CogVideoX-Fun-V1.1生成的视频,使其更好地符合人类偏好。 |
|
||||
|
||||
<details>
|
||||
<summary>(Obsolete) V1.0:</summary>
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-2b-InP) | 官方的图生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-5b-InP) | 官方的图生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
</details>
|
||||
# 未来计划
|
||||
- 支持CogVideoX-5b。
|
||||
|
||||
# 参考文献
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
|
||||
- Wan2.1: https://github.com/Wan-Video/Wan2.1/
|
||||
- Wan2.2: https://github.com/Wan-Video/Wan2.2/
|
||||
- Diffusers: https://github.com/huggingface/diffusers
|
||||
- Qwen-Image: https://github.com/QwenLM/Qwen-Image
|
||||
- Self-Forcing: https://github.com/guandeh17/Self-Forcing
|
||||
- Flux: https://github.com/black-forest-labs/flux
|
||||
- Flux2: https://github.com/black-forest-labs/flux2
|
||||
- HunyuanVideo: https://github.com/Tencent-Hunyuan/HunyuanVideo
|
||||
- ComfyUI-KJNodes: https://github.com/kijai/ComfyUI-KJNodes
|
||||
- ComfyUI-EasyAnimateWrapper: https://github.com/kijai/ComfyUI-EasyAnimateWrapper
|
||||
- ComfyUI-CameraCtrl-Wrapper: https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper
|
||||
- CameraCtrl: https://github.com/hehao13/CameraCtrl
|
||||
|
||||
# 许可证
|
||||
本项目采用 [Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE).
|
||||
|
||||
CogVideoX-2B 模型 (包括其对应的Transformers模块,VAE模块) 根据 [Apache 2.0 协议](LICENSE) 许可证发布。
|
||||
|
||||
CogVideoX-5B 模型(Transformer 模块)在[CogVideoX许可证](https://huggingface.co/THUDM/CogVideoX-5b/blob/main/LICENSE)下发布.
|
||||
CogVideoX-2B 模型 (包括其对应的Transformers模块,VAE模块) 根据 [Apache 2.0 协议](LICENSE) 许可证发布。
|
||||
@@ -0,0 +1,46 @@
|
||||
import time
|
||||
import torch
|
||||
|
||||
from cogvideox.api.api import infer_forward_api, update_diffusion_transformer_api, update_edition_api
|
||||
from cogvideox.ui.ui import ui_modelscope, ui_eas, ui
|
||||
|
||||
if __name__ == "__main__":
|
||||
# Choose the ui mode
|
||||
ui_mode = "normal"
|
||||
|
||||
# Low gpu memory mode, this is used when the GPU memory is under 16GB
|
||||
low_gpu_memory_mode = False
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
|
||||
# Server ip
|
||||
server_name = "0.0.0.0"
|
||||
server_port = 7860
|
||||
|
||||
# Params below is used when ui_mode = "modelscope"
|
||||
model_name = "models/Diffusion_Transformer/CogVideoX-Fun-2b-InP"
|
||||
savedir_sample = "samples"
|
||||
|
||||
if ui_mode == "modelscope":
|
||||
demo, controller = ui_modelscope(model_name, savedir_sample, low_gpu_memory_mode, weight_dtype)
|
||||
elif ui_mode == "eas":
|
||||
demo, controller = ui_eas(model_name, savedir_sample)
|
||||
else:
|
||||
demo, controller = ui(low_gpu_memory_mode, weight_dtype)
|
||||
|
||||
# launch gradio
|
||||
app, _, _ = demo.queue(status_update_rate=1).launch(
|
||||
server_name=server_name,
|
||||
server_port=server_port,
|
||||
prevent_thread_lock=True
|
||||
)
|
||||
|
||||
# launch api
|
||||
infer_forward_api(None, app, controller)
|
||||
update_diffusion_transformer_api(None, app, controller)
|
||||
update_edition_api(None, app, controller)
|
||||
|
||||
# not close the python
|
||||
while True:
|
||||
time.sleep(5)
|
||||

|
Before Width: | Height: | Size: 128 KiB |

|
Before Width: | Height: | Size: 477 KiB |

|
Before Width: | Height: | Size: 569 KiB |
@@ -1,82 +0,0 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9999164298554373 -0.012928004685808521 0.0 0.0 0.012928004685808521 0.9999164298554373 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9996657333896874 -0.025853848581176044 0.0 0.0 0.025853848581176044 0.9996657333896874 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.99924795250423 -0.03877537125681671 0.0 0.0 0.03877537125681671 0.99924795250423 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9986631570270832 -0.051690413005694553 0.0 0.0 0.051690413005694553 0.9986631570270832 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.997911444701132 -0.06459681520399763 0.0 0.0 0.06459681520399763 0.997911444701132 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.996992941167792 -0.07749242067193093 0.0 0.0 0.07749242067193093 0.996992941167792 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9959077999460093 -0.0903750740342681 0.0 0.0 0.0903750740342681 0.9959077999460093 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9946562024066015 -0.10324262208060146 0.0 0.0 0.10324262208060146 0.9946562024066015 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.993238357741943 -0.11609291412523022 0.0 0.0 0.11609291412523022 0.993238357741943 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9916545029310012 -0.12892380236662665 0.0 0.0 0.12892380236662665 0.9916545029310012 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.989904902699727 -0.14173314224642042 0.0 0.0 0.14173314224642042 0.989904902699727 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.987989849476809 -0.15451879280784048 0.0 0.0 0.15451879280784048 0.987989849476809 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9859096633447965 -0.16727861705355532 0.0 0.0 0.16727861705355532 0.9859096633447965 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9836646919866011 -0.18001048230285133 0.0 0.0 0.18001048230285133 0.9836646919866011 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9812553106273847 -0.19271226054808965 0.0 0.0 0.19271226054808965 0.9812553106273847 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9786819219718442 -0.20538182881038197 0.0 0.0 0.20538182881038197 0.9786819219718442 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9759449561369036 -0.21801706949442584 0.0 0.0 0.21801706949442584 0.9759449561369036 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9730448705798238 -0.23061587074244014 0.0 0.0 0.23061587074244014 0.9730448705798238 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9699821500217435 -0.24317612678714165 0.0 0.0 0.24317612678714165 0.9699821500217435 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.966757306366662 -0.25569573830370357 0.0 0.0 0.25569573830370357 0.966757306366662 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9633708786158803 -0.26817261276063736 0.0 0.0 0.26817261276063736 0.9633708786158803 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9598234327779119 -0.2806046647695387 0.0 0.0 0.2806046647695387 0.9598234327779119 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9561155617738797 -0.29298981643364064 0.0 0.0 0.29298981643364064 0.9561155617738797 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9522478853384153 -0.3053259976951131 0.0 0.0 0.3053259976951131 0.9522478853384153 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9482210499160765 -0.3176111466810532 0.0 0.0 0.3176111466810532 0.9482210499160765 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9440357285533 -0.3298432100481077 0.0 0.0 0.3298432100481077 0.9440357285533 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9396926207859084 -0.34202014332566866 0.0 0.0 0.34202014332566866 0.9396926207859084 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9351924525221897 -0.35413991125758754 0.0 0.0 0.35413991125758754 0.9351924525221897 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9305359759215686 -0.36620048814234796 0.0 0.0 0.36620048814234796 0.9305359759215686 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9257239692688904 -0.3781998581716424 0.0 0.0 0.3781998581716424 0.9257239692688904 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9207572368443384 -0.3901360157672949 0.0 0.0 0.3901360157672949 0.9207572368443384 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9156366087890059 -0.40200696591647384 0.0 0.0 0.40200696591647384 0.9156366087890059 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9103629409661467 -0.4138107245051391 0.0 0.0 0.4138107245051391 0.9103629409661467 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9049371148181253 -0.4255453186496674 0.0 0.0 0.4255453186496674 0.9049371148181253 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8993600372190931 -0.4372087870266006 0.0 0.0 0.4372087870266006 0.8993600372190931 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8936326403234123 -0.4487991802004621 0.0 0.0 0.4487991802004621 0.8936326403234123 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.887755881409856 -0.4603145609495856 0.0 0.0 0.4603145609495856 0.887755881409856 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.881730742721608 -0.4717530045899035 0.0 0.0 0.4717530045899035 0.881730742721608 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8755582313020909 -0.4831125992966384 0.0 0.0 0.4831125992966384 0.8755582313020909 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8692393788266478 -0.4943914464238468 0.0 0.0 0.4943914464238468 0.8692393788266478 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8627752414301085 -0.5055876608217589 0.0 0.0 0.5055876608217589 0.8627752414301085 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8561668995302665 -0.5166993711518628 0.0 0.0 0.5166993711518628 0.8561668995302665 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8494154576472973 -0.5277247201996818 0.0 0.0 0.5277247201996818 0.8494154576472973 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8425220442191496 -0.5386618651851877 0.0 0.0 0.5386618651851877 0.8425220442191496 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8354878114129365 -0.549508978070806 0.0 0.0 0.549508978070806 0.8354878114129365 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.828313934932363 -0.5602642458669524 0.0 0.0 0.5602642458669524 0.828313934932363 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8210016138212185 -0.5709258709350582 0.0 0.0 0.5709258709350582 0.8210016138212185 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8135520702629676 -0.5814920712880266 0.0 0.0 0.5814920712880266 0.8135520702629676 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8059665493764744 -0.5919610808880759 0.0 0.0 0.5919610808880759 0.8059665493764744 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.798246319007893 -0.6023311499419145 0.0 0.0 0.6023311499419145 0.798246319007893 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7903926695187593 -0.6126005451932028 0.0 0.0 0.6126005451932028 0.7903926695187593 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7824069135703198 -0.622767550212249 0.0 0.0 0.622767550212249 0.7824069135703198 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7742903859041323 -0.632830465682895 0.0 0.0 0.632830465682895 0.7742903859041323 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7660444431189781 -0.6427876096865393 0.0 0.0 0.6427876096865393 0.7660444431189781 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7576704634441179 -0.6526373179832544 0.0 0.0 0.6526373179832544 0.7576704634441179 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.749169846508936 -0.6623779442899478 0.0 0.0 0.6623779442899478 0.749169846508936 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7405440131090046 -0.6720078605555224 0.0 0.0 0.6720078605555224 0.7405440131090046 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7317944049686121 -0.6815254572329892 0.0 0.0 0.6815254572329892 0.7317944049686121 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7229224844997929 -0.6909291435484877 0.0 0.0 0.6909291435484877 0.7229224844997929 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7139297345578991 -0.7002173477671684 0.0 0.0 0.7002173477671684 0.7139297345578991 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7048176581937561 -0.7093885174558928 0.0 0.0 0.7093885174558928 0.7048176581937561 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.695587778402442 -0.7184411197427074 0.0 0.0 0.7184411197427074 0.695587778402442 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6862416378687336 -0.7273736415730486 0.0 0.0 0.7273736415730486 0.6862416378687336 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6767807987092621 -0.7361845899626351 0.0 0.0 0.7361845899626351 0.6767807987092621 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6672068422114197 -0.7448724922470058 0.0 0.0 0.7448724922470058 0.6672068422114197 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6575213685690637 -0.7534358963276606 0.0 0.0 0.7534358963276606 0.6575213685690637 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.647725996615059 -0.761873370914766 0.0 0.0 0.761873370914766 0.647725996615059 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6378223635507061 -0.7701835057663796 0.0 0.0 0.7701835057663796 0.6378223635507061 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6278121246720987 -0.7783649119241599 0.0 0.0 0.7783649119241599 0.6278121246720987 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6176969530934572 -0.7864162219455162 0.0 0.0 0.7864162219455162 0.6176969530934572 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6074785394674836 -0.7943360901321637 0.0 0.0 0.7943360901321637 0.6074785394674836 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5971585917027863 -0.8021231927550437 0.0 0.0 0.8021231927550437 0.5971585917027863 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5867388346784178 -0.8097762282755726 0.0 0.0 0.8097762282755726 0.5867388346784178 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5762210099555805 -0.8172939175631805 0.0 0.0 0.8172939175631805 0.5762210099555805 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5656068754865388 -0.8246750041091067 0.0 0.0 0.8246750041091067 0.5656068754865388 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.554898205320797 -0.8319182542364115 0.0 0.0 0.8319182542364115 0.554898205320797 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5440967893085827 -0.8390224573061746 0.0 0.0 0.8390224573061746 0.5440967893085827 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5332044328016914 -0.845986425919841 0.0 0.0 0.845986425919841 0.5332044328016914 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5222229563517384 -0.852808996117683 0.0 0.0 0.852808996117683 0.5222229563517384 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5111541954058733 -0.8594890275733451 0.0 0.0 0.8594890275733451 0.5111541954058733 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
@@ -1,82 +0,0 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9999164298554373 0.012928004685808521 0.0 0.0 -0.012928004685808521 0.9999164298554373 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9996657333896874 0.025853848581176044 0.0 0.0 -0.025853848581176044 0.9996657333896874 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.99924795250423 0.03877537125681671 0.0 0.0 -0.03877537125681671 0.99924795250423 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9986631570270832 0.051690413005694553 0.0 0.0 -0.051690413005694553 0.9986631570270832 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.997911444701132 0.06459681520399763 0.0 0.0 -0.06459681520399763 0.997911444701132 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.996992941167792 0.07749242067193093 0.0 0.0 -0.07749242067193093 0.996992941167792 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9959077999460093 0.0903750740342681 0.0 0.0 -0.0903750740342681 0.9959077999460093 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9946562024066015 0.10324262208060146 0.0 0.0 -0.10324262208060146 0.9946562024066015 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.993238357741943 0.11609291412523022 0.0 0.0 -0.11609291412523022 0.993238357741943 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9916545029310012 0.12892380236662665 0.0 0.0 -0.12892380236662665 0.9916545029310012 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.989904902699727 0.14173314224642042 0.0 0.0 -0.14173314224642042 0.989904902699727 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.987989849476809 0.15451879280784048 0.0 0.0 -0.15451879280784048 0.987989849476809 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9859096633447965 0.16727861705355532 0.0 0.0 -0.16727861705355532 0.9859096633447965 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9836646919866011 0.18001048230285133 0.0 0.0 -0.18001048230285133 0.9836646919866011 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9812553106273847 0.19271226054808965 0.0 0.0 -0.19271226054808965 0.9812553106273847 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9786819219718442 0.20538182881038197 0.0 0.0 -0.20538182881038197 0.9786819219718442 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9759449561369036 0.21801706949442584 0.0 0.0 -0.21801706949442584 0.9759449561369036 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9730448705798238 0.23061587074244014 0.0 0.0 -0.23061587074244014 0.9730448705798238 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9699821500217435 0.24317612678714165 0.0 0.0 -0.24317612678714165 0.9699821500217435 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.966757306366662 0.25569573830370357 0.0 0.0 -0.25569573830370357 0.966757306366662 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9633708786158803 0.26817261276063736 0.0 0.0 -0.26817261276063736 0.9633708786158803 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9598234327779119 0.2806046647695387 0.0 0.0 -0.2806046647695387 0.9598234327779119 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9561155617738797 0.29298981643364064 0.0 0.0 -0.29298981643364064 0.9561155617738797 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9522478853384153 0.3053259976951131 0.0 0.0 -0.3053259976951131 0.9522478853384153 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9482210499160765 0.3176111466810532 0.0 0.0 -0.3176111466810532 0.9482210499160765 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9440357285533 0.3298432100481077 0.0 0.0 -0.3298432100481077 0.9440357285533 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9396926207859084 0.34202014332566866 0.0 0.0 -0.34202014332566866 0.9396926207859084 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9351924525221897 0.35413991125758754 0.0 0.0 -0.35413991125758754 0.9351924525221897 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9305359759215686 0.36620048814234796 0.0 0.0 -0.36620048814234796 0.9305359759215686 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9257239692688904 0.3781998581716424 0.0 0.0 -0.3781998581716424 0.9257239692688904 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9207572368443384 0.3901360157672949 0.0 0.0 -0.3901360157672949 0.9207572368443384 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9156366087890059 0.40200696591647384 0.0 0.0 -0.40200696591647384 0.9156366087890059 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9103629409661467 0.4138107245051391 0.0 0.0 -0.4138107245051391 0.9103629409661467 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9049371148181253 0.4255453186496674 0.0 0.0 -0.4255453186496674 0.9049371148181253 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8993600372190931 0.4372087870266006 0.0 0.0 -0.4372087870266006 0.8993600372190931 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8936326403234123 0.4487991802004621 0.0 0.0 -0.4487991802004621 0.8936326403234123 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.887755881409856 0.4603145609495856 0.0 0.0 -0.4603145609495856 0.887755881409856 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.881730742721608 0.4717530045899035 0.0 0.0 -0.4717530045899035 0.881730742721608 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8755582313020909 0.4831125992966384 0.0 0.0 -0.4831125992966384 0.8755582313020909 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8692393788266478 0.4943914464238468 0.0 0.0 -0.4943914464238468 0.8692393788266478 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8627752414301085 0.5055876608217589 0.0 0.0 -0.5055876608217589 0.8627752414301085 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8561668995302665 0.5166993711518628 0.0 0.0 -0.5166993711518628 0.8561668995302665 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8494154576472973 0.5277247201996818 0.0 0.0 -0.5277247201996818 0.8494154576472973 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8425220442191496 0.5386618651851877 0.0 0.0 -0.5386618651851877 0.8425220442191496 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8354878114129365 0.549508978070806 0.0 0.0 -0.549508978070806 0.8354878114129365 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.828313934932363 0.5602642458669524 0.0 0.0 -0.5602642458669524 0.828313934932363 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8210016138212185 0.5709258709350582 0.0 0.0 -0.5709258709350582 0.8210016138212185 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8135520702629676 0.5814920712880266 0.0 0.0 -0.5814920712880266 0.8135520702629676 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8059665493764744 0.5919610808880759 0.0 0.0 -0.5919610808880759 0.8059665493764744 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.798246319007893 0.6023311499419145 0.0 0.0 -0.6023311499419145 0.798246319007893 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7903926695187593 0.6126005451932028 0.0 0.0 -0.6126005451932028 0.7903926695187593 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7824069135703198 0.622767550212249 0.0 0.0 -0.622767550212249 0.7824069135703198 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7742903859041323 0.632830465682895 0.0 0.0 -0.632830465682895 0.7742903859041323 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7660444431189781 0.6427876096865393 0.0 0.0 -0.6427876096865393 0.7660444431189781 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7576704634441179 0.6526373179832544 0.0 0.0 -0.6526373179832544 0.7576704634441179 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.749169846508936 0.6623779442899478 0.0 0.0 -0.6623779442899478 0.749169846508936 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7405440131090046 0.6720078605555224 0.0 0.0 -0.6720078605555224 0.7405440131090046 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7317944049686121 0.6815254572329892 0.0 0.0 -0.6815254572329892 0.7317944049686121 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7229224844997929 0.6909291435484877 0.0 0.0 -0.6909291435484877 0.7229224844997929 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7139297345578991 0.7002173477671684 0.0 0.0 -0.7002173477671684 0.7139297345578991 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7048176581937561 0.7093885174558928 0.0 0.0 -0.7093885174558928 0.7048176581937561 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.695587778402442 0.7184411197427074 0.0 0.0 -0.7184411197427074 0.695587778402442 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6862416378687336 0.7273736415730486 0.0 0.0 -0.7273736415730486 0.6862416378687336 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6767807987092621 0.7361845899626351 0.0 0.0 -0.7361845899626351 0.6767807987092621 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6672068422114197 0.7448724922470058 0.0 0.0 -0.7448724922470058 0.6672068422114197 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6575213685690637 0.7534358963276606 0.0 0.0 -0.7534358963276606 0.6575213685690637 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.647725996615059 0.761873370914766 0.0 0.0 -0.761873370914766 0.647725996615059 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6378223635507061 0.7701835057663796 0.0 0.0 -0.7701835057663796 0.6378223635507061 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6278121246720987 0.7783649119241599 0.0 0.0 -0.7783649119241599 0.6278121246720987 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6176969530934572 0.7864162219455162 0.0 0.0 -0.7864162219455162 0.6176969530934572 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6074785394674836 0.7943360901321637 0.0 0.0 -0.7943360901321637 0.6074785394674836 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5971585917027863 0.8021231927550437 0.0 0.0 -0.8021231927550437 0.5971585917027863 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5867388346784178 0.8097762282755726 0.0 0.0 -0.8097762282755726 0.5867388346784178 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5762210099555805 0.8172939175631805 0.0 0.0 -0.8172939175631805 0.5762210099555805 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5656068754865388 0.8246750041091067 0.0 0.0 -0.8246750041091067 0.5656068754865388 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.554898205320797 0.8319182542364115 0.0 0.0 -0.8319182542364115 0.554898205320797 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5440967893085827 0.8390224573061746 0.0 0.0 -0.8390224573061746 0.5440967893085827 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5332044328016914 0.845986425919841 0.0 0.0 -0.845986425919841 0.5332044328016914 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5222229563517384 0.852808996117683 0.0 0.0 -0.852808996117683 0.5222229563517384 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5111541954058733 0.8594890275733451 0.0 0.0 -0.8594890275733451 0.5111541954058733 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
@@ -1,82 +0,0 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.018518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.037037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.05555555555555555 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.07407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.09259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.1111111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.12962962962962962 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.14814814814814814 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.16666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.18518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.2222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.24074074074074073 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.25925925925925924 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.2777777777777778 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.31481481481481477 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.35185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.37037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.38888888888888884 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.42592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.4629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.48148148148148145 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5185185185185185 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.537037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5740740740740741 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.611111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.6296296296296295 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.6481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.6666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.6851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8148148148148148 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8333333333333334 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8703703703703705 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9259259259259258 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9814814814814815 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.0185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.0555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.0925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1111111111111112 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1296296296296298 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1666666666666667 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.2407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.2777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3148148148148149 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3703703703703702 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.425925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.462962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.4814814814814814 0.0 0.0 1.0 0.0
|
||||
@@ -1,82 +0,0 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.018518518518518517 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.037037037037037035 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.05555555555555555 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.07407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.09259259259259259 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.1111111111111111 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.12962962962962962 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.14814814814814814 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.16666666666666666 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.18518518518518517 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.24074074074074073 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.25925925925925924 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2777777777777778 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.31481481481481477 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.3333333333333333 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.35185185185185186 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.37037037037037035 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.38888888888888884 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.42592592592592593 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4629629629629629 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.48148148148148145 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5185185185185185 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.537037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5555555555555556 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5740740740740741 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5925925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.611111111111111 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6296296296296295 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6481481481481481 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6666666666666666 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6851851851851851 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7592592592592593 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7777777777777777 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8148148148148148 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8333333333333334 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8518518518518519 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8703703703703705 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8888888888888888 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9259259259259258 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9629629629629629 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9814814814814815 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0185185185185186 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0555555555555556 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0925925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1111111111111112 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1296296296296298 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1481481481481481 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1666666666666667 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1851851851851851 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.259259259259259 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2777777777777777 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3148148148148149 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3333333333333333 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3518518518518519 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3703703703703702 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3888888888888888 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.425925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.462962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4814814814814814 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
@@ -1,82 +0,0 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.018518518518518517 0.0 1.0 0.0 -0.018518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.037037037037037035 0.0 1.0 0.0 -0.037037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.05555555555555555 0.0 1.0 0.0 -0.05555555555555555 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.07407407407407407 0.0 1.0 0.0 -0.07407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.09259259259259259 0.0 1.0 0.0 -0.09259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.1111111111111111 0.0 1.0 0.0 -0.1111111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.12962962962962962 0.0 1.0 0.0 -0.12962962962962962 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.14814814814814814 0.0 1.0 0.0 -0.14814814814814814 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.16666666666666666 0.0 1.0 0.0 -0.16666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.18518518518518517 0.0 1.0 0.0 -0.18518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2037037037037037 0.0 1.0 0.0 -0.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2222222222222222 0.0 1.0 0.0 -0.2222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.24074074074074073 0.0 1.0 0.0 -0.24074074074074073 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.25925925925925924 0.0 1.0 0.0 -0.25925925925925924 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2777777777777778 0.0 1.0 0.0 -0.2777777777777778 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2962962962962963 0.0 1.0 0.0 -0.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.31481481481481477 0.0 1.0 0.0 -0.31481481481481477 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.3333333333333333 0.0 1.0 0.0 -0.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.35185185185185186 0.0 1.0 0.0 -0.35185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.37037037037037035 0.0 1.0 0.0 -0.37037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.38888888888888884 0.0 1.0 0.0 -0.38888888888888884 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4074074074074074 0.0 1.0 0.0 -0.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.42592592592592593 0.0 1.0 0.0 -0.42592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4444444444444444 0.0 1.0 0.0 -0.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4629629629629629 0.0 1.0 0.0 -0.4629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.48148148148148145 0.0 1.0 0.0 -0.48148148148148145 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5 0.0 1.0 0.0 -0.5 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5185185185185185 0.0 1.0 0.0 -0.5185185185185185 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.537037037037037 0.0 1.0 0.0 -0.537037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5555555555555556 0.0 1.0 0.0 -0.5555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5740740740740741 0.0 1.0 0.0 -0.5740740740740741 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5925925925925926 0.0 1.0 0.0 -0.5925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.611111111111111 0.0 1.0 0.0 -0.611111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6296296296296295 0.0 1.0 0.0 -0.6296296296296295 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6481481481481481 0.0 1.0 0.0 -0.6481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6666666666666666 0.0 1.0 0.0 -0.6666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6851851851851851 0.0 1.0 0.0 -0.6851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7037037037037037 0.0 1.0 0.0 -0.7037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7222222222222222 0.0 1.0 0.0 -0.7222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7407407407407407 0.0 1.0 0.0 -0.7407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7592592592592593 0.0 1.0 0.0 -0.7592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7777777777777777 0.0 1.0 0.0 -0.7777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7962962962962963 0.0 1.0 0.0 -0.7962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8148148148148148 0.0 1.0 0.0 -0.8148148148148148 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8333333333333334 0.0 1.0 0.0 -0.8333333333333334 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8518518518518519 0.0 1.0 0.0 -0.8518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8703703703703705 0.0 1.0 0.0 -0.8703703703703705 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8888888888888888 0.0 1.0 0.0 -0.8888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9074074074074074 0.0 1.0 0.0 -0.9074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9259259259259258 0.0 1.0 0.0 -0.9259259259259258 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9444444444444444 0.0 1.0 0.0 -0.9444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9629629629629629 0.0 1.0 0.0 -0.9629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9814814814814815 0.0 1.0 0.0 -0.9814814814814815 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0 0.0 1.0 0.0 -1.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0185185185185186 0.0 1.0 0.0 -1.0185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.037037037037037 0.0 1.0 0.0 -1.037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0555555555555556 0.0 1.0 0.0 -1.0555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.074074074074074 0.0 1.0 0.0 -1.074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0925925925925926 0.0 1.0 0.0 -1.0925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1111111111111112 0.0 1.0 0.0 -1.1111111111111112 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1296296296296298 0.0 1.0 0.0 -1.1296296296296298 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1481481481481481 0.0 1.0 0.0 -1.1481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1666666666666667 0.0 1.0 0.0 -1.1666666666666667 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1851851851851851 0.0 1.0 0.0 -1.1851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2037037037037037 0.0 1.0 0.0 -1.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.222222222222222 0.0 1.0 0.0 -1.222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2407407407407407 0.0 1.0 0.0 -1.2407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.259259259259259 0.0 1.0 0.0 -1.259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2777777777777777 0.0 1.0 0.0 -1.2777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2962962962962963 0.0 1.0 0.0 -1.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3148148148148149 0.0 1.0 0.0 -1.3148148148148149 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3333333333333333 0.0 1.0 0.0 -1.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3518518518518519 0.0 1.0 0.0 -1.3518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3703703703703702 0.0 1.0 0.0 -1.3703703703703702 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3888888888888888 0.0 1.0 0.0 -1.3888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4074074074074074 0.0 1.0 0.0 -1.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.425925925925926 0.0 1.0 0.0 -1.425925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4444444444444444 0.0 1.0 0.0 -1.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.462962962962963 0.0 1.0 0.0 -1.462962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4814814814814814 0.0 1.0 0.0 -1.4814814814814814 0.0 0.0 1.0 0.0
|
||||
@@ -1,82 +0,0 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.018518518518518517 0.0 1.0 0.0 0.018518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.037037037037037035 0.0 1.0 0.0 0.037037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.05555555555555555 0.0 1.0 0.0 0.05555555555555555 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.07407407407407407 0.0 1.0 0.0 0.07407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.09259259259259259 0.0 1.0 0.0 0.09259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.1111111111111111 0.0 1.0 0.0 0.1111111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.12962962962962962 0.0 1.0 0.0 0.12962962962962962 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.14814814814814814 0.0 1.0 0.0 0.14814814814814814 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.16666666666666666 0.0 1.0 0.0 0.16666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.18518518518518517 0.0 1.0 0.0 0.18518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2037037037037037 0.0 1.0 0.0 0.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2222222222222222 0.0 1.0 0.0 0.2222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.24074074074074073 0.0 1.0 0.0 0.24074074074074073 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.25925925925925924 0.0 1.0 0.0 0.25925925925925924 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2777777777777778 0.0 1.0 0.0 0.2777777777777778 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2962962962962963 0.0 1.0 0.0 0.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.31481481481481477 0.0 1.0 0.0 0.31481481481481477 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.3333333333333333 0.0 1.0 0.0 0.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.35185185185185186 0.0 1.0 0.0 0.35185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.37037037037037035 0.0 1.0 0.0 0.37037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.38888888888888884 0.0 1.0 0.0 0.38888888888888884 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4074074074074074 0.0 1.0 0.0 0.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.42592592592592593 0.0 1.0 0.0 0.42592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4444444444444444 0.0 1.0 0.0 0.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4629629629629629 0.0 1.0 0.0 0.4629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.48148148148148145 0.0 1.0 0.0 0.48148148148148145 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5 0.0 1.0 0.0 0.5 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5185185185185185 0.0 1.0 0.0 0.5185185185185185 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.537037037037037 0.0 1.0 0.0 0.537037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5555555555555556 0.0 1.0 0.0 0.5555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5740740740740741 0.0 1.0 0.0 0.5740740740740741 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5925925925925926 0.0 1.0 0.0 0.5925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.611111111111111 0.0 1.0 0.0 0.611111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6296296296296295 0.0 1.0 0.0 0.6296296296296295 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6481481481481481 0.0 1.0 0.0 0.6481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6666666666666666 0.0 1.0 0.0 0.6666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6851851851851851 0.0 1.0 0.0 0.6851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7037037037037037 0.0 1.0 0.0 0.7037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7222222222222222 0.0 1.0 0.0 0.7222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7407407407407407 0.0 1.0 0.0 0.7407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7592592592592593 0.0 1.0 0.0 0.7592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7777777777777777 0.0 1.0 0.0 0.7777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7962962962962963 0.0 1.0 0.0 0.7962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8148148148148148 0.0 1.0 0.0 0.8148148148148148 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8333333333333334 0.0 1.0 0.0 0.8333333333333334 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8518518518518519 0.0 1.0 0.0 0.8518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8703703703703705 0.0 1.0 0.0 0.8703703703703705 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8888888888888888 0.0 1.0 0.0 0.8888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9074074074074074 0.0 1.0 0.0 0.9074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9259259259259258 0.0 1.0 0.0 0.9259259259259258 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9444444444444444 0.0 1.0 0.0 0.9444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9629629629629629 0.0 1.0 0.0 0.9629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9814814814814815 0.0 1.0 0.0 0.9814814814814815 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0 0.0 1.0 0.0 1.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0185185185185186 0.0 1.0 0.0 1.0185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.037037037037037 0.0 1.0 0.0 1.037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0555555555555556 0.0 1.0 0.0 1.0555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.074074074074074 0.0 1.0 0.0 1.074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0925925925925926 0.0 1.0 0.0 1.0925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1111111111111112 0.0 1.0 0.0 1.1111111111111112 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1296296296296298 0.0 1.0 0.0 1.1296296296296298 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1481481481481481 0.0 1.0 0.0 1.1481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1666666666666667 0.0 1.0 0.0 1.1666666666666667 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1851851851851851 0.0 1.0 0.0 1.1851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2037037037037037 0.0 1.0 0.0 1.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.222222222222222 0.0 1.0 0.0 1.222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2407407407407407 0.0 1.0 0.0 1.2407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.259259259259259 0.0 1.0 0.0 1.259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2777777777777777 0.0 1.0 0.0 1.2777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2962962962962963 0.0 1.0 0.0 1.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3148148148148149 0.0 1.0 0.0 1.3148148148148149 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3333333333333333 0.0 1.0 0.0 1.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3518518518518519 0.0 1.0 0.0 1.3518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3703703703703702 0.0 1.0 0.0 1.3703703703703702 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3888888888888888 0.0 1.0 0.0 1.3888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4074074074074074 0.0 1.0 0.0 1.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.425925925925926 0.0 1.0 0.0 1.425925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4444444444444444 0.0 1.0 0.0 1.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.462962962962963 0.0 1.0 0.0 1.462962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4814814814814814 0.0 1.0 0.0 1.4814814814814814 0.0 0.0 1.0 0.0
|
||||
@@ -1,82 +0,0 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.018518518518518517 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.037037037037037035 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.05555555555555555 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.07407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.09259259259259259 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.1111111111111111 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.12962962962962962 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.14814814814814814 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.16666666666666666 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.18518518518518517 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.24074074074074073 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.25925925925925924 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2777777777777778 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.31481481481481477 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.3333333333333333 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.35185185185185186 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.37037037037037035 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.38888888888888884 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.42592592592592593 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4629629629629629 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.48148148148148145 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5185185185185185 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.537037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5555555555555556 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5740740740740741 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5925925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.611111111111111 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6296296296296295 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6481481481481481 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6666666666666666 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6851851851851851 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7592592592592593 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7777777777777777 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8148148148148148 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8333333333333334 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8518518518518519 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8703703703703705 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8888888888888888 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9259259259259258 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9629629629629629 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9814814814814815 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0185185185185186 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0555555555555556 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0925925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1111111111111112 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1296296296296298 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1481481481481481 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1666666666666667 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1851851851851851 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.259259259259259 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2777777777777777 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3148148148148149 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3333333333333333 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3518518518518519 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3703703703703702 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3888888888888888 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.425925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.462962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4814814814814814 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
@@ -1,82 +0,0 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.0 0.0 1.0 0.0 -0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.018518518518518517 0.0 1.0 0.0 -0.018518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.037037037037037035 0.0 1.0 0.0 -0.037037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.05555555555555555 0.0 1.0 0.0 -0.05555555555555555 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.07407407407407407 0.0 1.0 0.0 -0.07407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.09259259259259259 0.0 1.0 0.0 -0.09259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.1111111111111111 0.0 1.0 0.0 -0.1111111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.12962962962962962 0.0 1.0 0.0 -0.12962962962962962 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.14814814814814814 0.0 1.0 0.0 -0.14814814814814814 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.16666666666666666 0.0 1.0 0.0 -0.16666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.18518518518518517 0.0 1.0 0.0 -0.18518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2037037037037037 0.0 1.0 0.0 -0.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2222222222222222 0.0 1.0 0.0 -0.2222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.24074074074074073 0.0 1.0 0.0 -0.24074074074074073 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.25925925925925924 0.0 1.0 0.0 -0.25925925925925924 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2777777777777778 0.0 1.0 0.0 -0.2777777777777778 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2962962962962963 0.0 1.0 0.0 -0.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.31481481481481477 0.0 1.0 0.0 -0.31481481481481477 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.3333333333333333 0.0 1.0 0.0 -0.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.35185185185185186 0.0 1.0 0.0 -0.35185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.37037037037037035 0.0 1.0 0.0 -0.37037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.38888888888888884 0.0 1.0 0.0 -0.38888888888888884 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4074074074074074 0.0 1.0 0.0 -0.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.42592592592592593 0.0 1.0 0.0 -0.42592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4444444444444444 0.0 1.0 0.0 -0.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4629629629629629 0.0 1.0 0.0 -0.4629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.48148148148148145 0.0 1.0 0.0 -0.48148148148148145 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5 0.0 1.0 0.0 -0.5 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5185185185185185 0.0 1.0 0.0 -0.5185185185185185 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.537037037037037 0.0 1.0 0.0 -0.537037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5555555555555556 0.0 1.0 0.0 -0.5555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5740740740740741 0.0 1.0 0.0 -0.5740740740740741 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5925925925925926 0.0 1.0 0.0 -0.5925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.611111111111111 0.0 1.0 0.0 -0.611111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6296296296296295 0.0 1.0 0.0 -0.6296296296296295 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6481481481481481 0.0 1.0 0.0 -0.6481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6666666666666666 0.0 1.0 0.0 -0.6666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6851851851851851 0.0 1.0 0.0 -0.6851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7037037037037037 0.0 1.0 0.0 -0.7037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7222222222222222 0.0 1.0 0.0 -0.7222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7407407407407407 0.0 1.0 0.0 -0.7407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7592592592592593 0.0 1.0 0.0 -0.7592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7777777777777777 0.0 1.0 0.0 -0.7777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7962962962962963 0.0 1.0 0.0 -0.7962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8148148148148148 0.0 1.0 0.0 -0.8148148148148148 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8333333333333334 0.0 1.0 0.0 -0.8333333333333334 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8518518518518519 0.0 1.0 0.0 -0.8518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8703703703703705 0.0 1.0 0.0 -0.8703703703703705 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8888888888888888 0.0 1.0 0.0 -0.8888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9074074074074074 0.0 1.0 0.0 -0.9074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9259259259259258 0.0 1.0 0.0 -0.9259259259259258 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9444444444444444 0.0 1.0 0.0 -0.9444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9629629629629629 0.0 1.0 0.0 -0.9629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9814814814814815 0.0 1.0 0.0 -0.9814814814814815 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0 0.0 1.0 0.0 -1.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0185185185185186 0.0 1.0 0.0 -1.0185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.037037037037037 0.0 1.0 0.0 -1.037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0555555555555556 0.0 1.0 0.0 -1.0555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.074074074074074 0.0 1.0 0.0 -1.074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0925925925925926 0.0 1.0 0.0 -1.0925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1111111111111112 0.0 1.0 0.0 -1.1111111111111112 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1296296296296298 0.0 1.0 0.0 -1.1296296296296298 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1481481481481481 0.0 1.0 0.0 -1.1481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1666666666666667 0.0 1.0 0.0 -1.1666666666666667 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1851851851851851 0.0 1.0 0.0 -1.1851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2037037037037037 0.0 1.0 0.0 -1.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.222222222222222 0.0 1.0 0.0 -1.222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2407407407407407 0.0 1.0 0.0 -1.2407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.259259259259259 0.0 1.0 0.0 -1.259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2777777777777777 0.0 1.0 0.0 -1.2777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2962962962962963 0.0 1.0 0.0 -1.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3148148148148149 0.0 1.0 0.0 -1.3148148148148149 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3333333333333333 0.0 1.0 0.0 -1.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3518518518518519 0.0 1.0 0.0 -1.3518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3703703703703702 0.0 1.0 0.0 -1.3703703703703702 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3888888888888888 0.0 1.0 0.0 -1.3888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4074074074074074 0.0 1.0 0.0 -1.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.425925925925926 0.0 1.0 0.0 -1.425925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4444444444444444 0.0 1.0 0.0 -1.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.462962962962963 0.0 1.0 0.0 -1.462962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4814814814814814 0.0 1.0 0.0 -1.4814814814814814 0.0 0.0 1.0 0.0
|
||||
@@ -1,82 +0,0 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.018518518518518517 0.0 1.0 0.0 0.018518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.037037037037037035 0.0 1.0 0.0 0.037037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.05555555555555555 0.0 1.0 0.0 0.05555555555555555 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.07407407407407407 0.0 1.0 0.0 0.07407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.09259259259259259 0.0 1.0 0.0 0.09259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.1111111111111111 0.0 1.0 0.0 0.1111111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.12962962962962962 0.0 1.0 0.0 0.12962962962962962 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.14814814814814814 0.0 1.0 0.0 0.14814814814814814 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.16666666666666666 0.0 1.0 0.0 0.16666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.18518518518518517 0.0 1.0 0.0 0.18518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2037037037037037 0.0 1.0 0.0 0.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2222222222222222 0.0 1.0 0.0 0.2222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.24074074074074073 0.0 1.0 0.0 0.24074074074074073 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.25925925925925924 0.0 1.0 0.0 0.25925925925925924 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2777777777777778 0.0 1.0 0.0 0.2777777777777778 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2962962962962963 0.0 1.0 0.0 0.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.31481481481481477 0.0 1.0 0.0 0.31481481481481477 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.3333333333333333 0.0 1.0 0.0 0.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.35185185185185186 0.0 1.0 0.0 0.35185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.37037037037037035 0.0 1.0 0.0 0.37037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.38888888888888884 0.0 1.0 0.0 0.38888888888888884 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4074074074074074 0.0 1.0 0.0 0.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.42592592592592593 0.0 1.0 0.0 0.42592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4444444444444444 0.0 1.0 0.0 0.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4629629629629629 0.0 1.0 0.0 0.4629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.48148148148148145 0.0 1.0 0.0 0.48148148148148145 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5 0.0 1.0 0.0 0.5 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5185185185185185 0.0 1.0 0.0 0.5185185185185185 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.537037037037037 0.0 1.0 0.0 0.537037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5555555555555556 0.0 1.0 0.0 0.5555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5740740740740741 0.0 1.0 0.0 0.5740740740740741 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5925925925925926 0.0 1.0 0.0 0.5925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.611111111111111 0.0 1.0 0.0 0.611111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6296296296296295 0.0 1.0 0.0 0.6296296296296295 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6481481481481481 0.0 1.0 0.0 0.6481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6666666666666666 0.0 1.0 0.0 0.6666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6851851851851851 0.0 1.0 0.0 0.6851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7037037037037037 0.0 1.0 0.0 0.7037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7222222222222222 0.0 1.0 0.0 0.7222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7407407407407407 0.0 1.0 0.0 0.7407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7592592592592593 0.0 1.0 0.0 0.7592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7777777777777777 0.0 1.0 0.0 0.7777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7962962962962963 0.0 1.0 0.0 0.7962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8148148148148148 0.0 1.0 0.0 0.8148148148148148 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8333333333333334 0.0 1.0 0.0 0.8333333333333334 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8518518518518519 0.0 1.0 0.0 0.8518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8703703703703705 0.0 1.0 0.0 0.8703703703703705 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8888888888888888 0.0 1.0 0.0 0.8888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9074074074074074 0.0 1.0 0.0 0.9074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9259259259259258 0.0 1.0 0.0 0.9259259259259258 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9444444444444444 0.0 1.0 0.0 0.9444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9629629629629629 0.0 1.0 0.0 0.9629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9814814814814815 0.0 1.0 0.0 0.9814814814814815 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0 0.0 1.0 0.0 1.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0185185185185186 0.0 1.0 0.0 1.0185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.037037037037037 0.0 1.0 0.0 1.037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0555555555555556 0.0 1.0 0.0 1.0555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.074074074074074 0.0 1.0 0.0 1.074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0925925925925926 0.0 1.0 0.0 1.0925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1111111111111112 0.0 1.0 0.0 1.1111111111111112 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1296296296296298 0.0 1.0 0.0 1.1296296296296298 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1481481481481481 0.0 1.0 0.0 1.1481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1666666666666667 0.0 1.0 0.0 1.1666666666666667 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1851851851851851 0.0 1.0 0.0 1.1851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2037037037037037 0.0 1.0 0.0 1.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.222222222222222 0.0 1.0 0.0 1.222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2407407407407407 0.0 1.0 0.0 1.2407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.259259259259259 0.0 1.0 0.0 1.259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2777777777777777 0.0 1.0 0.0 1.2777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2962962962962963 0.0 1.0 0.0 1.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3148148148148149 0.0 1.0 0.0 1.3148148148148149 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3333333333333333 0.0 1.0 0.0 1.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3518518518518519 0.0 1.0 0.0 1.3518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3703703703703702 0.0 1.0 0.0 1.3703703703703702 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3888888888888888 0.0 1.0 0.0 1.3888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4074074074074074 0.0 1.0 0.0 1.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.425925925925926 0.0 1.0 0.0 1.425925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4444444444444444 0.0 1.0 0.0 1.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.462962962962963 0.0 1.0 0.0 1.462962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4814814814814814 0.0 1.0 0.0 1.4814814814814814 0.0 0.0 1.0 0.0
|
||||
@@ -1,82 +0,0 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.018518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.037037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.05555555555555555 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.07407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.09259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.1111111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.12962962962962962 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.14814814814814814 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.16666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.18518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.2222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.24074074074074073 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.25925925925925924 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.2777777777777778 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.31481481481481477 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.35185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.37037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.38888888888888884 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.42592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.4629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.48148148148148145 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5185185185185185 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.537037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5740740740740741 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.611111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.6296296296296295 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.6481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.6666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.6851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8148148148148148 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8333333333333334 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8703703703703705 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9259259259259258 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9814814814814815 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.0185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.0555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.0925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1111111111111112 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1296296296296298 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1666666666666667 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.2407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.2777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3148148148148149 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3703703703703702 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.425925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.462962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.4814814814814814 0.0 0.0 1.0 0.0
|
||||
@@ -1,82 +0,0 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.037037037037037035
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.07407407407407407
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.1111111111111111
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.14814814814814814
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.18518518518518517
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.2222222222222222
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.25925925925925924
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.2962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.3333333333333333
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.37037037037037035
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.4074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.4444444444444444
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.48148148148148145
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.5185185185185185
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.5555555555555556
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.5925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.6296296296296295
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.6666666666666666
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.7037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.7407407407407407
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.7777777777777777
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.8148148148148148
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.8518518518518519
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.8888888888888888
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.9259259259259258
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.9629629629629629
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.1111111111111112
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.1481481481481481
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.1851851851851851
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.222222222222222
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.259259259259259
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.2962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.3333333333333333
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.3703703703703702
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.4074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.4444444444444444
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.4814814814814814
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.5185185185185186
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.5555555555555554
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.5925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.6296296296296295
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.6666666666666667
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.7037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.740740740740741
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.7777777777777777
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.8148148148148149
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.8518518518518516
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.8888888888888888
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.9259259259259258
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.111111111111111
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.148148148148148
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.185185185185185
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.2222222222222223
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.2592592592592595
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.2962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.3333333333333335
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.3703703703703702
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.4074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.444444444444444
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.4814814814814814
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.518518518518518
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.5555555555555554
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.5925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.6296296296296298
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.6666666666666665
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.7037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.7407407407407405
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.7777777777777777
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.814814814814815
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.851851851851852
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.888888888888889
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.962962962962963
|
||||
@@ -1,82 +0,0 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.037037037037037035
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.07407407407407407
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.1111111111111111
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.14814814814814814
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.18518518518518517
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.2222222222222222
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.25925925925925924
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.2962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.3333333333333333
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.37037037037037035
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.4074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.4444444444444444
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.48148148148148145
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.5185185185185185
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.5555555555555556
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.5925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.6296296296296295
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.6666666666666666
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.7037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.7407407407407407
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.7777777777777777
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.8148148148148148
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.8518518518518519
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.8888888888888888
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.9259259259259258
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.9629629629629629
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.1111111111111112
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.1481481481481481
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.1851851851851851
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.222222222222222
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.259259259259259
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.2962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.3333333333333333
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.3703703703703702
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.4074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.4444444444444444
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.4814814814814814
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.5185185185185186
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.5555555555555554
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.5925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.6296296296296295
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.6666666666666667
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.7037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.740740740740741
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.7777777777777777
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.8148148148148149
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.8518518518518516
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.8888888888888888
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.9259259259259258
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.111111111111111
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.148148148148148
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.185185185185185
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.2222222222222223
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.2592592592592595
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.2962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.3333333333333335
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.3703703703703702
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.4074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.444444444444444
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.4814814814814814
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.518518518518518
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.5555555555555554
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.5925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.6296296296296298
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.6666666666666665
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.7037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.7407407407407405
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.7777777777777777
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.814814814814815
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.851851851851852
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.888888888888889
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.962962962962963
|
||||

|
Before Width: | Height: | Size: 43 KiB |

|
Before Width: | Height: | Size: 11 KiB |

|
Before Width: | Height: | Size: 42 KiB |

|
Before Width: | Height: | Size: 129 KiB |

|
Before Width: | Height: | Size: 226 KiB |
@@ -0,0 +1,149 @@
|
||||
import io
|
||||
import gc
|
||||
import base64
|
||||
import torch
|
||||
import gradio as gr
|
||||
import tempfile
|
||||
import hashlib
|
||||
import os
|
||||
|
||||
from fastapi import FastAPI
|
||||
from io import BytesIO
|
||||
from PIL import Image
|
||||
|
||||
# Function to encode a file to Base64
|
||||
def encode_file_to_base64(file_path):
|
||||
with open(file_path, "rb") as file:
|
||||
# Encode the data to Base64
|
||||
file_base64 = base64.b64encode(file.read())
|
||||
return file_base64
|
||||
|
||||
def update_edition_api(_: gr.Blocks, app: FastAPI, controller):
|
||||
@app.post("/cogvideox_fun/update_edition")
|
||||
def _update_edition_api(
|
||||
datas: dict,
|
||||
):
|
||||
edition = datas.get('edition', 'v2')
|
||||
|
||||
try:
|
||||
controller.update_edition(
|
||||
edition
|
||||
)
|
||||
comment = "Success"
|
||||
except Exception as e:
|
||||
torch.cuda.empty_cache()
|
||||
comment = f"Error. error information is {str(e)}"
|
||||
|
||||
return {"message": comment}
|
||||
|
||||
def update_diffusion_transformer_api(_: gr.Blocks, app: FastAPI, controller):
|
||||
@app.post("/cogvideox_fun/update_diffusion_transformer")
|
||||
def _update_diffusion_transformer_api(
|
||||
datas: dict,
|
||||
):
|
||||
diffusion_transformer_path = datas.get('diffusion_transformer_path', 'none')
|
||||
|
||||
try:
|
||||
controller.update_diffusion_transformer(
|
||||
diffusion_transformer_path
|
||||
)
|
||||
comment = "Success"
|
||||
except Exception as e:
|
||||
torch.cuda.empty_cache()
|
||||
comment = f"Error. error information is {str(e)}"
|
||||
|
||||
return {"message": comment}
|
||||
|
||||
def save_base64_video(base64_string):
|
||||
video_data = base64.b64decode(base64_string)
|
||||
|
||||
md5_hash = hashlib.md5(video_data).hexdigest()
|
||||
filename = f"{md5_hash}.mp4"
|
||||
|
||||
temp_dir = tempfile.gettempdir()
|
||||
file_path = os.path.join(temp_dir, filename)
|
||||
|
||||
with open(file_path, 'wb') as video_file:
|
||||
video_file.write(video_data)
|
||||
|
||||
return file_path
|
||||
|
||||
def infer_forward_api(_: gr.Blocks, app: FastAPI, controller):
|
||||
@app.post("/cogvideox_fun/infer_forward")
|
||||
def _infer_forward_api(
|
||||
datas: dict,
|
||||
):
|
||||
base_model_path = datas.get('base_model_path', 'none')
|
||||
lora_model_path = datas.get('lora_model_path', 'none')
|
||||
lora_alpha_slider = datas.get('lora_alpha_slider', 0.55)
|
||||
prompt_textbox = datas.get('prompt_textbox', None)
|
||||
negative_prompt_textbox = datas.get('negative_prompt_textbox', 'The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion.')
|
||||
sampler_dropdown = datas.get('sampler_dropdown', 'Euler')
|
||||
sample_step_slider = datas.get('sample_step_slider', 30)
|
||||
resize_method = datas.get('resize_method', "Generate by")
|
||||
width_slider = datas.get('width_slider', 672)
|
||||
height_slider = datas.get('height_slider', 384)
|
||||
base_resolution = datas.get('base_resolution', 512)
|
||||
is_image = datas.get('is_image', False)
|
||||
generation_method = datas.get('generation_method', False)
|
||||
length_slider = datas.get('length_slider', 144)
|
||||
overlap_video_length = datas.get('overlap_video_length', 4)
|
||||
partial_video_length = datas.get('partial_video_length', 72)
|
||||
cfg_scale_slider = datas.get('cfg_scale_slider', 6)
|
||||
start_image = datas.get('start_image', None)
|
||||
end_image = datas.get('end_image', None)
|
||||
validation_video = datas.get('validation_video', None)
|
||||
denoise_strength = datas.get('denoise_strength', 0.70)
|
||||
seed_textbox = datas.get("seed_textbox", 43)
|
||||
|
||||
generation_method = "Image Generation" if is_image else generation_method
|
||||
|
||||
if start_image is not None:
|
||||
start_image = base64.b64decode(start_image)
|
||||
start_image = [Image.open(BytesIO(start_image))]
|
||||
|
||||
if end_image is not None:
|
||||
end_image = base64.b64decode(end_image)
|
||||
end_image = [Image.open(BytesIO(end_image))]
|
||||
|
||||
if validation_video is not None:
|
||||
validation_video = save_base64_video(validation_video)
|
||||
|
||||
try:
|
||||
save_sample_path, comment = controller.generate(
|
||||
"",
|
||||
base_model_path,
|
||||
lora_model_path,
|
||||
lora_alpha_slider,
|
||||
prompt_textbox,
|
||||
negative_prompt_textbox,
|
||||
sampler_dropdown,
|
||||
sample_step_slider,
|
||||
resize_method,
|
||||
width_slider,
|
||||
height_slider,
|
||||
base_resolution,
|
||||
generation_method,
|
||||
length_slider,
|
||||
overlap_video_length,
|
||||
partial_video_length,
|
||||
cfg_scale_slider,
|
||||
start_image,
|
||||
end_image,
|
||||
validation_video,
|
||||
denoise_strength,
|
||||
seed_textbox,
|
||||
is_api = True,
|
||||
)
|
||||
except Exception as e:
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_sample_path = ""
|
||||
comment = f"Error. error information is {str(e)}"
|
||||
return {"message": comment}
|
||||
|
||||
if save_sample_path != "":
|
||||
return {"message": comment, "save_sample_path": save_sample_path, "base64_encoding": encode_file_to_base64(save_sample_path)}
|
||||
else:
|
||||
return {"message": comment, "save_sample_path": save_sample_path}
|
||||
@@ -0,0 +1,96 @@
|
||||
import base64
|
||||
import json
|
||||
import sys
|
||||
import time
|
||||
from datetime import datetime
|
||||
from io import BytesIO
|
||||
|
||||
import cv2
|
||||
import requests
|
||||
import base64
|
||||
|
||||
|
||||
def post_diffusion_transformer(diffusion_transformer_path, url='http://127.0.0.1:7860'):
|
||||
datas = json.dumps({
|
||||
"diffusion_transformer_path": diffusion_transformer_path
|
||||
})
|
||||
r = requests.post(f'{url}/cogvideox_fun/update_diffusion_transformer', data=datas, timeout=1500)
|
||||
data = r.content.decode('utf-8')
|
||||
return data
|
||||
|
||||
def post_update_edition(edition, url='http://0.0.0.0:7860'):
|
||||
datas = json.dumps({
|
||||
"edition": edition
|
||||
})
|
||||
r = requests.post(f'{url}/cogvideox_fun/update_edition', data=datas, timeout=1500)
|
||||
data = r.content.decode('utf-8')
|
||||
return data
|
||||
|
||||
def post_infer(generation_method, length_slider, url='http://127.0.0.1:7860'):
|
||||
datas = json.dumps({
|
||||
"base_model_path": "none",
|
||||
"motion_module_path": "none",
|
||||
"lora_model_path": "none",
|
||||
"lora_alpha_slider": 0.55,
|
||||
"prompt_textbox": "This video shows Mount saint helens, washington - the stunning scenery of a rocky mountains during golden hours - wide shot. A soaring drone footage captures the majestic beauty of a coastal cliff, its red and yellow stratified rock faces rich in color and against the vibrant turquoise of the sea.",
|
||||
"negative_prompt_textbox": "Strange motion trajectory, a poor composition and deformed video, worst quality, normal quality, low quality, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera",
|
||||
"sampler_dropdown": "Euler",
|
||||
"sample_step_slider": 30,
|
||||
"width_slider": 672,
|
||||
"height_slider": 384,
|
||||
"generation_method": "Video Generation",
|
||||
"length_slider": length_slider,
|
||||
"cfg_scale_slider": 6,
|
||||
"seed_textbox": 43,
|
||||
})
|
||||
r = requests.post(f'{url}/cogvideox_fun/infer_forward', data=datas, timeout=1500)
|
||||
data = r.content.decode('utf-8')
|
||||
return data
|
||||
|
||||
if __name__ == '__main__':
|
||||
# initiate time
|
||||
now_date = datetime.now()
|
||||
time_start = time.time()
|
||||
|
||||
# -------------------------- #
|
||||
# Step 1: update edition
|
||||
# -------------------------- #
|
||||
edition = "v3"
|
||||
outputs = post_update_edition(edition)
|
||||
print('Output update edition: ', outputs)
|
||||
|
||||
# -------------------------- #
|
||||
# Step 2: update edition
|
||||
# -------------------------- #
|
||||
diffusion_transformer_path = "models/Diffusion_Transformer/cogvideox_funV3-XL-2-512x512"
|
||||
outputs = post_diffusion_transformer(diffusion_transformer_path)
|
||||
print('Output update edition: ', outputs)
|
||||
|
||||
# -------------------------- #
|
||||
# Step 3: infer
|
||||
# -------------------------- #
|
||||
# "Video Generation" and "Image Generation"
|
||||
generation_method = "Video Generation"
|
||||
length_slider = 72
|
||||
outputs = post_infer(generation_method, length_slider)
|
||||
|
||||
# Get decoded data
|
||||
outputs = json.loads(outputs)
|
||||
base64_encoding = outputs["base64_encoding"]
|
||||
decoded_data = base64.b64decode(base64_encoding)
|
||||
|
||||
is_image = True if generation_method == "Image Generation" else False
|
||||
if is_image or length_slider == 1:
|
||||
file_path = "1.png"
|
||||
else:
|
||||
file_path = "1.mp4"
|
||||
with open(file_path, "wb") as file:
|
||||
file.write(decoded_data)
|
||||
|
||||
# End of record time
|
||||
# The calculated time difference is the execution time of the program, expressed in seconds / s
|
||||
time_end = time.time()
|
||||
time_sum = (time_end - time_start) % 60
|
||||
print('# --------------------------------------------------------- #')
|
||||
print(f'# Total expenditure: {time_sum}s')
|
||||
print('# --------------------------------------------------------- #')
|
||||
@@ -254,7 +254,7 @@ class AspectRatioBatchSampler(BatchSampler):
|
||||
width = int(width)
|
||||
ratio = height / width # self.dataset[idx]
|
||||
except Exception as e:
|
||||
print(e, self.dataset[idx], "This item is error, please check it.")
|
||||
print(e)
|
||||
continue
|
||||
# find the closest aspect ratio
|
||||
closest_ratio = min(self.aspect_ratios.keys(), key=lambda r: abs(float(r) - ratio))
|
||||
@@ -330,7 +330,7 @@ class AspectRatioBatchImageVideoSampler(BatchSampler):
|
||||
width = int(width)
|
||||
ratio = height / width # self.dataset[idx]
|
||||
except Exception as e:
|
||||
print(e, self.dataset[idx], "This item is error, please check it.")
|
||||
print(e)
|
||||
continue
|
||||
# find the closest aspect ratio
|
||||
closest_ratio = min(self.aspect_ratios.keys(), key=lambda r: abs(float(r) - ratio))
|
||||
@@ -365,7 +365,7 @@ class AspectRatioBatchImageVideoSampler(BatchSampler):
|
||||
width = int(width)
|
||||
ratio = height / width # self.dataset[idx]
|
||||
except Exception as e:
|
||||
print(e, self.dataset[idx], "This item is error, please check it.")
|
||||
print(e)
|
||||
continue
|
||||
# find the closest aspect ratio
|
||||
closest_ratio = min(self.aspect_ratios.keys(), key=lambda r: abs(float(r) - ratio))
|
||||
@@ -0,0 +1,76 @@
|
||||
import json
|
||||
import os
|
||||
import random
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchvision.transforms as transforms
|
||||
from PIL import Image
|
||||
from torch.utils.data.dataset import Dataset
|
||||
|
||||
|
||||
class CC15M(Dataset):
|
||||
def __init__(
|
||||
self,
|
||||
json_path,
|
||||
video_folder=None,
|
||||
resolution=512,
|
||||
enable_bucket=False,
|
||||
):
|
||||
print(f"loading annotations from {json_path} ...")
|
||||
self.dataset = json.load(open(json_path, 'r'))
|
||||
self.length = len(self.dataset)
|
||||
print(f"data scale: {self.length}")
|
||||
|
||||
self.enable_bucket = enable_bucket
|
||||
self.video_folder = video_folder
|
||||
|
||||
resolution = tuple(resolution) if not isinstance(resolution, int) else (resolution, resolution)
|
||||
self.pixel_transforms = transforms.Compose([
|
||||
transforms.Resize(resolution[0]),
|
||||
transforms.CenterCrop(resolution),
|
||||
transforms.ToTensor(),
|
||||
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
|
||||
])
|
||||
|
||||
def get_batch(self, idx):
|
||||
video_dict = self.dataset[idx]
|
||||
video_id, name = video_dict['file_path'], video_dict['text']
|
||||
|
||||
if self.video_folder is None:
|
||||
video_dir = video_id
|
||||
else:
|
||||
video_dir = os.path.join(self.video_folder, video_id)
|
||||
|
||||
pixel_values = Image.open(video_dir).convert("RGB")
|
||||
return pixel_values, name
|
||||
|
||||
def __len__(self):
|
||||
return self.length
|
||||
|
||||
def __getitem__(self, idx):
|
||||
while True:
|
||||
try:
|
||||
pixel_values, name = self.get_batch(idx)
|
||||
break
|
||||
except Exception as e:
|
||||
print(e)
|
||||
idx = random.randint(0, self.length-1)
|
||||
|
||||
if not self.enable_bucket:
|
||||
pixel_values = self.pixel_transforms(pixel_values)
|
||||
else:
|
||||
pixel_values = np.array(pixel_values)
|
||||
|
||||
sample = dict(pixel_values=pixel_values, text=name)
|
||||
return sample
|
||||
|
||||
if __name__ == "__main__":
|
||||
dataset = CC15M(
|
||||
csv_path="/mnt_wg/zhoumo.xjq/CCUtils/cc15m_add_index.json",
|
||||
resolution=512,
|
||||
)
|
||||
|
||||
dataloader = torch.utils.data.DataLoader(dataset, batch_size=4, num_workers=0,)
|
||||
for idx, batch in enumerate(dataloader):
|
||||
print(batch["pixel_values"].shape, len(batch["text"]))
|
||||
@@ -0,0 +1,324 @@
|
||||
import csv
|
||||
import io
|
||||
import json
|
||||
import math
|
||||
import os
|
||||
import random
|
||||
from threading import Thread
|
||||
|
||||
import albumentations
|
||||
import cv2
|
||||
import gc
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchvision.transforms as transforms
|
||||
|
||||
from func_timeout import func_timeout, FunctionTimedOut
|
||||
from decord import VideoReader
|
||||
from PIL import Image
|
||||
from torch.utils.data import BatchSampler, Sampler
|
||||
from torch.utils.data.dataset import Dataset
|
||||
from contextlib import contextmanager
|
||||
|
||||
VIDEO_READER_TIMEOUT = 20
|
||||
|
||||
def get_random_mask(shape):
|
||||
f, c, h, w = shape
|
||||
|
||||
if f != 1:
|
||||
mask_index = np.random.choice([0, 1, 2, 3, 4], p = [0.05, 0.3, 0.3, 0.3, 0.05]) # np.random.randint(0, 5)
|
||||
else:
|
||||
mask_index = np.random.choice([0, 1], p = [0.2, 0.8]) # np.random.randint(0, 2)
|
||||
mask = torch.zeros((f, 1, h, w), dtype=torch.uint8)
|
||||
|
||||
if mask_index == 0:
|
||||
center_x = torch.randint(0, w, (1,)).item()
|
||||
center_y = torch.randint(0, h, (1,)).item()
|
||||
block_size_x = torch.randint(w // 4, w // 4 * 3, (1,)).item() # 方块的宽度范围
|
||||
block_size_y = torch.randint(h // 4, h // 4 * 3, (1,)).item() # 方块的高度范围
|
||||
|
||||
start_x = max(center_x - block_size_x // 2, 0)
|
||||
end_x = min(center_x + block_size_x // 2, w)
|
||||
start_y = max(center_y - block_size_y // 2, 0)
|
||||
end_y = min(center_y + block_size_y // 2, h)
|
||||
mask[:, :, start_y:end_y, start_x:end_x] = 1
|
||||
elif mask_index == 1:
|
||||
mask[:, :, :, :] = 1
|
||||
elif mask_index == 2:
|
||||
mask_frame_index = np.random.randint(1, 5)
|
||||
mask[mask_frame_index:, :, :, :] = 1
|
||||
elif mask_index == 3:
|
||||
mask_frame_index = np.random.randint(1, 5)
|
||||
mask[mask_frame_index:-mask_frame_index, :, :, :] = 1
|
||||
elif mask_index == 4:
|
||||
center_x = torch.randint(0, w, (1,)).item()
|
||||
center_y = torch.randint(0, h, (1,)).item()
|
||||
block_size_x = torch.randint(w // 4, w // 4 * 3, (1,)).item() # 方块的宽度范围
|
||||
block_size_y = torch.randint(h // 4, h // 4 * 3, (1,)).item() # 方块的高度范围
|
||||
|
||||
start_x = max(center_x - block_size_x // 2, 0)
|
||||
end_x = min(center_x + block_size_x // 2, w)
|
||||
start_y = max(center_y - block_size_y // 2, 0)
|
||||
end_y = min(center_y + block_size_y // 2, h)
|
||||
|
||||
mask_frame_before = np.random.randint(0, f // 2)
|
||||
mask_frame_after = np.random.randint(f // 2, f)
|
||||
mask[mask_frame_before:mask_frame_after, :, start_y:end_y, start_x:end_x] = 1
|
||||
else:
|
||||
raise ValueError(f"The mask_index {mask_index} is not define")
|
||||
return mask
|
||||
|
||||
class ImageVideoSampler(BatchSampler):
|
||||
"""A sampler wrapper for grouping images with similar aspect ratio into a same batch.
|
||||
|
||||
Args:
|
||||
sampler (Sampler): Base sampler.
|
||||
dataset (Dataset): Dataset providing data information.
|
||||
batch_size (int): Size of mini-batch.
|
||||
drop_last (bool): If ``True``, the sampler will drop the last batch if
|
||||
its size would be less than ``batch_size``.
|
||||
aspect_ratios (dict): The predefined aspect ratios.
|
||||
"""
|
||||
|
||||
def __init__(self,
|
||||
sampler: Sampler,
|
||||
dataset: Dataset,
|
||||
batch_size: int,
|
||||
drop_last: bool = False
|
||||
) -> None:
|
||||
if not isinstance(sampler, Sampler):
|
||||
raise TypeError('sampler should be an instance of ``Sampler``, '
|
||||
f'but got {sampler}')
|
||||
if not isinstance(batch_size, int) or batch_size <= 0:
|
||||
raise ValueError('batch_size should be a positive integer value, '
|
||||
f'but got batch_size={batch_size}')
|
||||
self.sampler = sampler
|
||||
self.dataset = dataset
|
||||
self.batch_size = batch_size
|
||||
self.drop_last = drop_last
|
||||
|
||||
# buckets for each aspect ratio
|
||||
self.bucket = {'image':[], 'video':[]}
|
||||
|
||||
def __iter__(self):
|
||||
for idx in self.sampler:
|
||||
content_type = self.dataset.dataset[idx].get('type', 'image')
|
||||
self.bucket[content_type].append(idx)
|
||||
|
||||
# yield a batch of indices in the same aspect ratio group
|
||||
if len(self.bucket['video']) == self.batch_size:
|
||||
bucket = self.bucket['video']
|
||||
yield bucket[:]
|
||||
del bucket[:]
|
||||
elif len(self.bucket['image']) == self.batch_size:
|
||||
bucket = self.bucket['image']
|
||||
yield bucket[:]
|
||||
del bucket[:]
|
||||
|
||||
@contextmanager
|
||||
def VideoReader_contextmanager(*args, **kwargs):
|
||||
vr = VideoReader(*args, **kwargs)
|
||||
try:
|
||||
yield vr
|
||||
finally:
|
||||
del vr
|
||||
gc.collect()
|
||||
|
||||
def get_video_reader_batch(video_reader, batch_index):
|
||||
frames = video_reader.get_batch(batch_index).asnumpy()
|
||||
return frames
|
||||
|
||||
def resize_frame(frame, target_short_side):
|
||||
h, w, _ = frame.shape
|
||||
if h < w:
|
||||
if target_short_side > h:
|
||||
return frame
|
||||
new_h = target_short_side
|
||||
new_w = int(target_short_side * w / h)
|
||||
else:
|
||||
if target_short_side > w:
|
||||
return frame
|
||||
new_w = target_short_side
|
||||
new_h = int(target_short_side * h / w)
|
||||
|
||||
resized_frame = cv2.resize(frame, (new_w, new_h))
|
||||
return resized_frame
|
||||
|
||||
class ImageVideoDataset(Dataset):
|
||||
def __init__(
|
||||
self,
|
||||
ann_path, data_root=None,
|
||||
video_sample_size=512, video_sample_stride=4, video_sample_n_frames=16,
|
||||
image_sample_size=512,
|
||||
video_repeat=0,
|
||||
text_drop_ratio=-1,
|
||||
enable_bucket=False,
|
||||
video_length_drop_start=0.1,
|
||||
video_length_drop_end=0.9,
|
||||
enable_inpaint=False,
|
||||
):
|
||||
# Loading annotations from files
|
||||
print(f"loading annotations from {ann_path} ...")
|
||||
if ann_path.endswith('.csv'):
|
||||
with open(ann_path, 'r') as csvfile:
|
||||
dataset = list(csv.DictReader(csvfile))
|
||||
elif ann_path.endswith('.json'):
|
||||
dataset = json.load(open(ann_path))
|
||||
|
||||
self.data_root = data_root
|
||||
|
||||
# It's used to balance num of images and videos.
|
||||
self.dataset = []
|
||||
for data in dataset:
|
||||
if data.get('type', 'image') != 'video':
|
||||
self.dataset.append(data)
|
||||
if video_repeat > 0:
|
||||
for _ in range(video_repeat):
|
||||
for data in dataset:
|
||||
if data.get('type', 'image') == 'video':
|
||||
self.dataset.append(data)
|
||||
del dataset
|
||||
|
||||
self.length = len(self.dataset)
|
||||
print(f"data scale: {self.length}")
|
||||
# TODO: enable bucket training
|
||||
self.enable_bucket = enable_bucket
|
||||
self.text_drop_ratio = text_drop_ratio
|
||||
self.enable_inpaint = enable_inpaint
|
||||
|
||||
self.video_length_drop_start = video_length_drop_start
|
||||
self.video_length_drop_end = video_length_drop_end
|
||||
|
||||
# Video params
|
||||
self.video_sample_stride = video_sample_stride
|
||||
self.video_sample_n_frames = video_sample_n_frames
|
||||
self.video_sample_size = tuple(video_sample_size) if not isinstance(video_sample_size, int) else (video_sample_size, video_sample_size)
|
||||
self.video_transforms = transforms.Compose(
|
||||
[
|
||||
transforms.Resize(min(self.video_sample_size)),
|
||||
transforms.CenterCrop(self.video_sample_size),
|
||||
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
|
||||
]
|
||||
)
|
||||
|
||||
# Image params
|
||||
self.image_sample_size = tuple(image_sample_size) if not isinstance(image_sample_size, int) else (image_sample_size, image_sample_size)
|
||||
self.image_transforms = transforms.Compose([
|
||||
transforms.Resize(min(self.image_sample_size)),
|
||||
transforms.CenterCrop(self.image_sample_size),
|
||||
transforms.ToTensor(),
|
||||
transforms.Normalize([0.5, 0.5, 0.5],[0.5, 0.5, 0.5])
|
||||
])
|
||||
|
||||
self.larger_side_of_image_and_video = max(min(self.image_sample_size), min(self.video_sample_size))
|
||||
|
||||
def get_batch(self, idx):
|
||||
data_info = self.dataset[idx % len(self.dataset)]
|
||||
|
||||
if data_info.get('type', 'image')=='video':
|
||||
video_id, text = data_info['file_path'], data_info['text']
|
||||
|
||||
if self.data_root is None:
|
||||
video_dir = video_id
|
||||
else:
|
||||
video_dir = os.path.join(self.data_root, video_id)
|
||||
|
||||
with VideoReader_contextmanager(video_dir, num_threads=2) as video_reader:
|
||||
min_sample_n_frames = min(
|
||||
self.video_sample_n_frames,
|
||||
int(len(video_reader) * (self.video_length_drop_end - self.video_length_drop_start) // self.video_sample_stride)
|
||||
)
|
||||
if min_sample_n_frames == 0:
|
||||
raise ValueError(f"No Frames in video.")
|
||||
|
||||
video_length = int(self.video_length_drop_end * len(video_reader))
|
||||
clip_length = min(video_length, (min_sample_n_frames - 1) * self.video_sample_stride + 1)
|
||||
start_idx = random.randint(int(self.video_length_drop_start * video_length), video_length - clip_length) if video_length != clip_length else 0
|
||||
batch_index = np.linspace(start_idx, start_idx + clip_length - 1, min_sample_n_frames, dtype=int)
|
||||
|
||||
try:
|
||||
sample_args = (video_reader, batch_index)
|
||||
pixel_values = func_timeout(
|
||||
VIDEO_READER_TIMEOUT, get_video_reader_batch, args=sample_args
|
||||
)
|
||||
resized_frames = []
|
||||
for i in range(len(pixel_values)):
|
||||
frame = pixel_values[i]
|
||||
resized_frame = resize_frame(frame, self.larger_side_of_image_and_video)
|
||||
resized_frames.append(resized_frame)
|
||||
pixel_values = np.array(resized_frames)
|
||||
except FunctionTimedOut:
|
||||
raise ValueError(f"Read {idx} timeout.")
|
||||
except Exception as e:
|
||||
raise ValueError(f"Failed to extract frames from video. Error is {e}.")
|
||||
|
||||
if not self.enable_bucket:
|
||||
pixel_values = torch.from_numpy(pixel_values).permute(0, 3, 1, 2).contiguous()
|
||||
pixel_values = pixel_values / 255.
|
||||
del video_reader
|
||||
else:
|
||||
pixel_values = pixel_values
|
||||
|
||||
if not self.enable_bucket:
|
||||
pixel_values = self.video_transforms(pixel_values)
|
||||
|
||||
# Random use no text generation
|
||||
if random.random() < self.text_drop_ratio:
|
||||
text = ''
|
||||
return pixel_values, text, 'video'
|
||||
else:
|
||||
image_path, text = data_info['file_path'], data_info['text']
|
||||
if self.data_root is not None:
|
||||
image_path = os.path.join(self.data_root, image_path)
|
||||
image = Image.open(image_path).convert('RGB')
|
||||
if not self.enable_bucket:
|
||||
image = self.image_transforms(image).unsqueeze(0)
|
||||
else:
|
||||
image = np.expand_dims(np.array(image), 0)
|
||||
if random.random() < self.text_drop_ratio:
|
||||
text = ''
|
||||
return image, text, 'image'
|
||||
|
||||
def __len__(self):
|
||||
return self.length
|
||||
|
||||
def __getitem__(self, idx):
|
||||
data_info = self.dataset[idx % len(self.dataset)]
|
||||
data_type = data_info.get('type', 'image')
|
||||
while True:
|
||||
sample = {}
|
||||
try:
|
||||
data_info_local = self.dataset[idx % len(self.dataset)]
|
||||
data_type_local = data_info_local.get('type', 'image')
|
||||
if data_type_local != data_type:
|
||||
raise ValueError("data_type_local != data_type")
|
||||
|
||||
pixel_values, name, data_type = self.get_batch(idx)
|
||||
sample["pixel_values"] = pixel_values
|
||||
sample["text"] = name
|
||||
sample["data_type"] = data_type
|
||||
sample["idx"] = idx
|
||||
|
||||
if len(sample) > 0:
|
||||
break
|
||||
except Exception as e:
|
||||
print(e, self.dataset[idx % len(self.dataset)])
|
||||
idx = random.randint(0, self.length-1)
|
||||
|
||||
if self.enable_inpaint and not self.enable_bucket:
|
||||
mask = get_random_mask(pixel_values.size())
|
||||
mask_pixel_values = pixel_values * (1 - mask) + torch.ones_like(pixel_values) * -1 * mask
|
||||
sample["mask_pixel_values"] = mask_pixel_values
|
||||
sample["mask"] = mask
|
||||
|
||||
clip_pixel_values = sample["pixel_values"][0].permute(1, 2, 0).contiguous()
|
||||
clip_pixel_values = (clip_pixel_values * 0.5 + 0.5) * 255
|
||||
sample["clip_pixel_values"] = clip_pixel_values
|
||||
|
||||
ref_pixel_values = sample["pixel_values"][0].unsqueeze(0)
|
||||
if (mask == 1).all():
|
||||
ref_pixel_values = torch.ones_like(ref_pixel_values) * -1
|
||||
sample["ref_pixel_values"] = ref_pixel_values
|
||||
|
||||
return sample
|
||||
|
||||
@@ -0,0 +1,262 @@
|
||||
import csv
|
||||
import gc
|
||||
import io
|
||||
import json
|
||||
import math
|
||||
import os
|
||||
import random
|
||||
from contextlib import contextmanager
|
||||
from threading import Thread
|
||||
|
||||
import albumentations
|
||||
import cv2
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchvision.transforms as transforms
|
||||
from decord import VideoReader
|
||||
from einops import rearrange
|
||||
from func_timeout import FunctionTimedOut, func_timeout
|
||||
from PIL import Image
|
||||
from torch.utils.data import BatchSampler, Sampler
|
||||
from torch.utils.data.dataset import Dataset
|
||||
|
||||
VIDEO_READER_TIMEOUT = 20
|
||||
|
||||
def get_random_mask(shape):
|
||||
f, c, h, w = shape
|
||||
|
||||
mask_index = np.random.randint(0, 4)
|
||||
mask = torch.zeros((f, 1, h, w), dtype=torch.uint8)
|
||||
if mask_index == 0:
|
||||
mask[1:, :, :, :] = 1
|
||||
elif mask_index == 1:
|
||||
mask_frame_index = 1
|
||||
mask[mask_frame_index:-mask_frame_index, :, :, :] = 1
|
||||
elif mask_index == 2:
|
||||
center_x = torch.randint(0, w, (1,)).item()
|
||||
center_y = torch.randint(0, h, (1,)).item()
|
||||
block_size_x = torch.randint(w // 4, w // 4 * 3, (1,)).item() # 方块的宽度范围
|
||||
block_size_y = torch.randint(h // 4, h // 4 * 3, (1,)).item() # 方块的高度范围
|
||||
|
||||
start_x = max(center_x - block_size_x // 2, 0)
|
||||
end_x = min(center_x + block_size_x // 2, w)
|
||||
start_y = max(center_y - block_size_y // 2, 0)
|
||||
end_y = min(center_y + block_size_y // 2, h)
|
||||
mask[:, :, start_y:end_y, start_x:end_x] = 1
|
||||
elif mask_index == 3:
|
||||
center_x = torch.randint(0, w, (1,)).item()
|
||||
center_y = torch.randint(0, h, (1,)).item()
|
||||
block_size_x = torch.randint(w // 4, w // 4 * 3, (1,)).item() # 方块的宽度范围
|
||||
block_size_y = torch.randint(h // 4, h // 4 * 3, (1,)).item() # 方块的高度范围
|
||||
|
||||
start_x = max(center_x - block_size_x // 2, 0)
|
||||
end_x = min(center_x + block_size_x // 2, w)
|
||||
start_y = max(center_y - block_size_y // 2, 0)
|
||||
end_y = min(center_y + block_size_y // 2, h)
|
||||
|
||||
mask_frame_before = np.random.randint(0, f // 2)
|
||||
mask_frame_after = np.random.randint(f // 2, f)
|
||||
mask[mask_frame_before:mask_frame_after, :, start_y:end_y, start_x:end_x] = 1
|
||||
else:
|
||||
raise ValueError(f"The mask_index {mask_index} is not define")
|
||||
return mask
|
||||
|
||||
|
||||
@contextmanager
|
||||
def VideoReader_contextmanager(*args, **kwargs):
|
||||
vr = VideoReader(*args, **kwargs)
|
||||
try:
|
||||
yield vr
|
||||
finally:
|
||||
del vr
|
||||
gc.collect()
|
||||
|
||||
|
||||
def get_video_reader_batch(video_reader, batch_index):
|
||||
frames = video_reader.get_batch(batch_index).asnumpy()
|
||||
return frames
|
||||
|
||||
|
||||
class WebVid10M(Dataset):
|
||||
def __init__(
|
||||
self,
|
||||
csv_path, video_folder,
|
||||
sample_size=256, sample_stride=4, sample_n_frames=16,
|
||||
enable_bucket=False, enable_inpaint=False, is_image=False,
|
||||
):
|
||||
print(f"loading annotations from {csv_path} ...")
|
||||
with open(csv_path, 'r') as csvfile:
|
||||
self.dataset = list(csv.DictReader(csvfile))
|
||||
self.length = len(self.dataset)
|
||||
print(f"data scale: {self.length}")
|
||||
|
||||
self.video_folder = video_folder
|
||||
self.sample_stride = sample_stride
|
||||
self.sample_n_frames = sample_n_frames
|
||||
self.enable_bucket = enable_bucket
|
||||
self.enable_inpaint = enable_inpaint
|
||||
self.is_image = is_image
|
||||
|
||||
sample_size = tuple(sample_size) if not isinstance(sample_size, int) else (sample_size, sample_size)
|
||||
self.pixel_transforms = transforms.Compose([
|
||||
transforms.Resize(sample_size[0]),
|
||||
transforms.CenterCrop(sample_size),
|
||||
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
|
||||
])
|
||||
|
||||
def get_batch(self, idx):
|
||||
video_dict = self.dataset[idx]
|
||||
videoid, name, page_dir = video_dict['videoid'], video_dict['name'], video_dict['page_dir']
|
||||
|
||||
video_dir = os.path.join(self.video_folder, f"{videoid}.mp4")
|
||||
video_reader = VideoReader(video_dir)
|
||||
video_length = len(video_reader)
|
||||
|
||||
if not self.is_image:
|
||||
clip_length = min(video_length, (self.sample_n_frames - 1) * self.sample_stride + 1)
|
||||
start_idx = random.randint(0, video_length - clip_length)
|
||||
batch_index = np.linspace(start_idx, start_idx + clip_length - 1, self.sample_n_frames, dtype=int)
|
||||
else:
|
||||
batch_index = [random.randint(0, video_length - 1)]
|
||||
|
||||
if not self.enable_bucket:
|
||||
pixel_values = torch.from_numpy(video_reader.get_batch(batch_index).asnumpy()).permute(0, 3, 1, 2).contiguous()
|
||||
pixel_values = pixel_values / 255.
|
||||
del video_reader
|
||||
else:
|
||||
pixel_values = video_reader.get_batch(batch_index).asnumpy()
|
||||
|
||||
if self.is_image:
|
||||
pixel_values = pixel_values[0]
|
||||
return pixel_values, name
|
||||
|
||||
def __len__(self):
|
||||
return self.length
|
||||
|
||||
def __getitem__(self, idx):
|
||||
while True:
|
||||
try:
|
||||
pixel_values, name = self.get_batch(idx)
|
||||
break
|
||||
|
||||
except Exception as e:
|
||||
print("Error info:", e)
|
||||
idx = random.randint(0, self.length-1)
|
||||
|
||||
if not self.enable_bucket:
|
||||
pixel_values = self.pixel_transforms(pixel_values)
|
||||
if self.enable_inpaint:
|
||||
mask = get_random_mask(pixel_values.size())
|
||||
mask_pixel_values = pixel_values * (1 - mask) + torch.ones_like(pixel_values) * -1 * mask
|
||||
sample = dict(pixel_values=pixel_values, mask_pixel_values=mask_pixel_values, mask=mask, text=name)
|
||||
else:
|
||||
sample = dict(pixel_values=pixel_values, text=name)
|
||||
return sample
|
||||
|
||||
|
||||
class VideoDataset(Dataset):
|
||||
def __init__(
|
||||
self,
|
||||
json_path, video_folder=None,
|
||||
sample_size=256, sample_stride=4, sample_n_frames=16,
|
||||
enable_bucket=False, enable_inpaint=False
|
||||
):
|
||||
print(f"loading annotations from {json_path} ...")
|
||||
self.dataset = json.load(open(json_path, 'r'))
|
||||
self.length = len(self.dataset)
|
||||
print(f"data scale: {self.length}")
|
||||
|
||||
self.video_folder = video_folder
|
||||
self.sample_stride = sample_stride
|
||||
self.sample_n_frames = sample_n_frames
|
||||
self.enable_bucket = enable_bucket
|
||||
self.enable_inpaint = enable_inpaint
|
||||
|
||||
sample_size = tuple(sample_size) if not isinstance(sample_size, int) else (sample_size, sample_size)
|
||||
self.pixel_transforms = transforms.Compose(
|
||||
[
|
||||
transforms.Resize(sample_size[0]),
|
||||
transforms.CenterCrop(sample_size),
|
||||
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
|
||||
]
|
||||
)
|
||||
|
||||
def get_batch(self, idx):
|
||||
video_dict = self.dataset[idx]
|
||||
video_id, name = video_dict['file_path'], video_dict['text']
|
||||
|
||||
if self.video_folder is None:
|
||||
video_dir = video_id
|
||||
else:
|
||||
video_dir = os.path.join(self.video_folder, video_id)
|
||||
|
||||
with VideoReader_contextmanager(video_dir, num_threads=2) as video_reader:
|
||||
video_length = len(video_reader)
|
||||
|
||||
clip_length = min(video_length, (self.sample_n_frames - 1) * self.sample_stride + 1)
|
||||
start_idx = random.randint(0, video_length - clip_length)
|
||||
batch_index = np.linspace(start_idx, start_idx + clip_length - 1, self.sample_n_frames, dtype=int)
|
||||
|
||||
try:
|
||||
sample_args = (video_reader, batch_index)
|
||||
pixel_values = func_timeout(
|
||||
VIDEO_READER_TIMEOUT, get_video_reader_batch, args=sample_args
|
||||
)
|
||||
except FunctionTimedOut:
|
||||
raise ValueError(f"Read {idx} timeout.")
|
||||
except Exception as e:
|
||||
raise ValueError(f"Failed to extract frames from video. Error is {e}.")
|
||||
|
||||
if not self.enable_bucket:
|
||||
pixel_values = torch.from_numpy(pixel_values).permute(0, 3, 1, 2).contiguous()
|
||||
pixel_values = pixel_values / 255.
|
||||
del video_reader
|
||||
else:
|
||||
pixel_values = pixel_values
|
||||
|
||||
return pixel_values, name
|
||||
|
||||
def __len__(self):
|
||||
return self.length
|
||||
|
||||
def __getitem__(self, idx):
|
||||
while True:
|
||||
try:
|
||||
pixel_values, name = self.get_batch(idx)
|
||||
break
|
||||
|
||||
except Exception as e:
|
||||
print("Error info:", e)
|
||||
idx = random.randint(0, self.length-1)
|
||||
|
||||
if not self.enable_bucket:
|
||||
pixel_values = self.pixel_transforms(pixel_values)
|
||||
if self.enable_inpaint:
|
||||
mask = get_random_mask(pixel_values.size())
|
||||
mask_pixel_values = pixel_values * (1 - mask) + torch.ones_like(pixel_values) * -1 * mask
|
||||
sample = dict(pixel_values=pixel_values, mask_pixel_values=mask_pixel_values, mask=mask, text=name)
|
||||
else:
|
||||
sample = dict(pixel_values=pixel_values, text=name)
|
||||
return sample
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
if 1:
|
||||
dataset = VideoDataset(
|
||||
json_path="/home/zhoumo.xjq/disk3/datasets/webvidval/results_2M_val.json",
|
||||
sample_size=256,
|
||||
sample_stride=4, sample_n_frames=16,
|
||||
)
|
||||
|
||||
if 0:
|
||||
dataset = WebVid10M(
|
||||
csv_path="/mnt/petrelfs/guoyuwei/projects/datasets/webvid/results_2M_val.csv",
|
||||
video_folder="/mnt/petrelfs/guoyuwei/projects/datasets/webvid/2M_val",
|
||||
sample_size=256,
|
||||
sample_stride=4, sample_n_frames=16,
|
||||
is_image=False,
|
||||
)
|
||||
|
||||
dataloader = torch.utils.data.DataLoader(dataset, batch_size=4, num_workers=0,)
|
||||
for idx, batch in enumerate(dataloader):
|
||||
print(batch["pixel_values"].shape, len(batch["text"]))
|
||||
@@ -0,0 +1,110 @@
|
||||
from typing import Optional
|
||||
import torch
|
||||
from flash_attn import flash_attn_func
|
||||
from einops import rearrange
|
||||
|
||||
from diffusers.models.attention import Attention
|
||||
from diffusers.models.embeddings import apply_rotary_emb
|
||||
|
||||
|
||||
class CogVideoXSWAAttnProcessor2_0:
|
||||
r"""
|
||||
Processor for implementing scaled dot-product attention for the CogVideoX model. It applies a rotary embedding on
|
||||
query and key vectors, but does not include spatial normalization.
|
||||
"""
|
||||
|
||||
def __init__(self, window_size=1024):
|
||||
self.window_size = window_size
|
||||
|
||||
def __call__(
|
||||
self,
|
||||
attn: Attention,
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: torch.Tensor,
|
||||
attention_mask: Optional[torch.Tensor] = None,
|
||||
image_rotary_emb: Optional[torch.Tensor] = None,
|
||||
num_frames: int = None,
|
||||
height: int = None,
|
||||
width: int = None,
|
||||
) -> torch.Tensor:
|
||||
text_seq_length = encoder_hidden_states.size(1)
|
||||
|
||||
hidden_states = torch.cat([encoder_hidden_states, hidden_states], dim=1)
|
||||
|
||||
batch_size, sequence_length, _ = (
|
||||
hidden_states.shape if encoder_hidden_states is None else encoder_hidden_states.shape
|
||||
)
|
||||
|
||||
if attention_mask is not None:
|
||||
attention_mask = attn.prepare_attention_mask(attention_mask, sequence_length, batch_size)
|
||||
attention_mask = attention_mask.view(batch_size, attn.heads, -1, attention_mask.shape[-1])
|
||||
|
||||
query = attn.to_q(hidden_states)
|
||||
key = attn.to_k(hidden_states)
|
||||
value = attn.to_v(hidden_states)
|
||||
|
||||
inner_dim = key.shape[-1]
|
||||
head_dim = inner_dim // attn.heads
|
||||
|
||||
query = query.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
key = key.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
value = value.view(batch_size, -1, attn.heads, head_dim) # .transpose(1, 2)
|
||||
|
||||
if attn.norm_q is not None:
|
||||
query = attn.norm_q(query)
|
||||
if attn.norm_k is not None:
|
||||
key = attn.norm_k(key)
|
||||
|
||||
# Apply RoPE if needed
|
||||
if image_rotary_emb is not None:
|
||||
|
||||
query[:, :, text_seq_length:] = apply_rotary_emb(query[:, :, text_seq_length:], image_rotary_emb)
|
||||
if not attn.is_cross_attention:
|
||||
key[:, :, text_seq_length:] = apply_rotary_emb(key[:, :, text_seq_length:], image_rotary_emb)
|
||||
|
||||
query = query.transpose(1, 2).to(value)
|
||||
key = key.transpose(1, 2).to(value)
|
||||
|
||||
interval = max((query.size(1) - text_seq_length) // (self.window_size - 256), 1)
|
||||
cross_key = torch.cat([key[:, :text_seq_length], key[:, text_seq_length::interval]], dim=1)
|
||||
cross_val = torch.cat([value[:, :text_seq_length], value[:, text_seq_length::interval]], dim=1)
|
||||
cross_hidden_states = flash_attn_func(query, cross_key, cross_val, dropout_p=0.0, causal=False)
|
||||
query_txt = query[:, :text_seq_length]
|
||||
key_txt = key[:, :text_seq_length]
|
||||
value_txt = value[:, :text_seq_length]
|
||||
querys = torch.tensor_split(query[:, text_seq_length:], 6, 2)
|
||||
keys = torch.tensor_split(key[:, text_seq_length:], 6, 2)
|
||||
values = torch.tensor_split(value[:, text_seq_length:], 6, 2)
|
||||
new_querys = [querys[0]]
|
||||
new_keys = [keys[0]]
|
||||
new_values = [values[0]]
|
||||
for index, mode in enumerate(["bs (f h w) hn hd -> bs (f w h) hn hd", "bs (f h w) hn hd -> bs (h f w) hn hd", "bs (f h w) hn hd -> bs (h w f) hn hd",
|
||||
"bs (f h w) hn hd -> bs (w f h) hn hd", "bs (f h w) hn hd -> bs (w h f) hn hd"]):
|
||||
new_querys.append(rearrange(querys[index + 1], mode, f=num_frames, h=height, w=width))
|
||||
new_keys.append(rearrange(keys[index + 1], mode, f=num_frames, h=height, w=width))
|
||||
new_values.append(rearrange(values[index + 1], mode, f=num_frames, h=height, w=width))
|
||||
query = torch.cat([query_txt, torch.cat(new_querys, dim=2)], dim=1)
|
||||
key = torch.cat([key_txt, torch.cat(new_keys, dim=2)], dim=1)
|
||||
value = torch.cat([value_txt, torch.cat(new_values, dim=2)], dim=1)
|
||||
|
||||
hidden_states = flash_attn_func(query, key, value, dropout_p=0.0, causal=False, window_size=(self.window_size, self.window_size))
|
||||
hidden_states_txt = hidden_states[:, :text_seq_length]
|
||||
hidden_states = torch.tensor_split(hidden_states[:, text_seq_length:], 6, 2)
|
||||
new_hidden_states = [hidden_states[0]]
|
||||
for index, mode in enumerate(["bs (f w h) hn hd -> bs (f h w) hn hd", "bs (h f w) hn hd -> bs (f h w) hn hd", "bs (h w f) hn hd -> bs (f h w) hn hd",
|
||||
"bs (w f h) hn hd -> bs (f h w) hn hd", "bs (w h f) hn hd -> bs (f h w) hn hd"]):
|
||||
new_hidden_states.append(rearrange(hidden_states[index + 1], mode, f=num_frames, h=height, w=width))
|
||||
hidden_states = torch.cat([hidden_states_txt, torch.cat(new_hidden_states, dim=2)], dim=1) + cross_hidden_states
|
||||
|
||||
|
||||
hidden_states = hidden_states.reshape(batch_size, -1, attn.heads * head_dim)
|
||||
|
||||
# linear proj
|
||||
hidden_states = attn.to_out[0](hidden_states)
|
||||
# dropout
|
||||
hidden_states = attn.to_out[1](hidden_states)
|
||||
|
||||
encoder_hidden_states, hidden_states = hidden_states.split(
|
||||
[text_seq_length, hidden_states.size(1) - text_seq_length], dim=1
|
||||
)
|
||||
return hidden_states, encoder_hidden_states
|
||||
@@ -13,14 +13,12 @@
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from typing import Dict, Optional, Tuple, Union
|
||||
from typing import Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
import json
|
||||
import os
|
||||
|
||||
from diffusers.configuration_utils import ConfigMixin, register_to_config
|
||||
from diffusers.loaders.single_file_model import FromOriginalModelMixin
|
||||
@@ -43,9 +41,7 @@ class CogVideoXSafeConv3d(nn.Conv3d):
|
||||
"""
|
||||
|
||||
def forward(self, input: torch.Tensor) -> torch.Tensor:
|
||||
memory_count = (
|
||||
(input.shape[0] * input.shape[1] * input.shape[2] * input.shape[3] * input.shape[4]) * 2 / 1024**3
|
||||
)
|
||||
memory_count = torch.prod(torch.tensor(input.shape)).item() * 2 / 1024**3
|
||||
|
||||
# Set to 2GB, suitable for CuDNN
|
||||
if memory_count > 2:
|
||||
@@ -96,13 +92,11 @@ class CogVideoXCausalConv3d(nn.Module):
|
||||
|
||||
time_kernel_size, height_kernel_size, width_kernel_size = kernel_size
|
||||
|
||||
# TODO(aryan): configure calculation based on stride and dilation in the future.
|
||||
# Since CogVideoX does not use it, it is currently tailored to "just work" with Mochi
|
||||
time_pad = time_kernel_size - 1
|
||||
height_pad = (height_kernel_size - 1) // 2
|
||||
width_pad = (width_kernel_size - 1) // 2
|
||||
|
||||
self.pad_mode = pad_mode
|
||||
time_pad = dilation * (time_kernel_size - 1) + (1 - stride)
|
||||
height_pad = height_kernel_size // 2
|
||||
width_pad = width_kernel_size // 2
|
||||
|
||||
self.height_pad = height_pad
|
||||
self.width_pad = width_pad
|
||||
self.time_pad = time_pad
|
||||
@@ -111,7 +105,7 @@ class CogVideoXCausalConv3d(nn.Module):
|
||||
self.temporal_dim = 2
|
||||
self.time_kernel_size = time_kernel_size
|
||||
|
||||
stride = stride if isinstance(stride, tuple) else (stride, 1, 1)
|
||||
stride = (stride, 1, 1)
|
||||
dilation = (dilation, 1, 1)
|
||||
self.conv = CogVideoXSafeConv3d(
|
||||
in_channels=in_channels,
|
||||
@@ -121,30 +115,34 @@ class CogVideoXCausalConv3d(nn.Module):
|
||||
dilation=dilation,
|
||||
)
|
||||
|
||||
def fake_context_parallel_forward(
|
||||
self, inputs: torch.Tensor, conv_cache: Optional[torch.Tensor] = None
|
||||
) -> torch.Tensor:
|
||||
if self.pad_mode == "replicate":
|
||||
inputs = F.pad(inputs, self.time_causal_padding, mode="replicate")
|
||||
else:
|
||||
kernel_size = self.time_kernel_size
|
||||
if kernel_size > 1:
|
||||
cached_inputs = [conv_cache] if conv_cache is not None else [inputs[:, :, :1]] * (kernel_size - 1)
|
||||
inputs = torch.cat(cached_inputs + [inputs], dim=2)
|
||||
self.conv_cache = None
|
||||
|
||||
def fake_context_parallel_forward(self, inputs: torch.Tensor) -> torch.Tensor:
|
||||
kernel_size = self.time_kernel_size
|
||||
if kernel_size > 1:
|
||||
cached_inputs = (
|
||||
[self.conv_cache] if self.conv_cache is not None else [inputs[:, :, :1]] * (kernel_size - 1)
|
||||
)
|
||||
inputs = torch.cat(cached_inputs + [inputs], dim=2)
|
||||
return inputs
|
||||
|
||||
def forward(self, inputs: torch.Tensor, conv_cache: Optional[torch.Tensor] = None) -> torch.Tensor:
|
||||
inputs = self.fake_context_parallel_forward(inputs, conv_cache)
|
||||
def _clear_fake_context_parallel_cache(self):
|
||||
del self.conv_cache
|
||||
self.conv_cache = None
|
||||
|
||||
if self.pad_mode == "replicate":
|
||||
conv_cache = None
|
||||
else:
|
||||
padding_2d = (self.width_pad, self.width_pad, self.height_pad, self.height_pad)
|
||||
conv_cache = inputs[:, :, -self.time_kernel_size + 1 :].clone()
|
||||
inputs = F.pad(inputs, padding_2d, mode="constant", value=0)
|
||||
def forward(self, inputs: torch.Tensor) -> torch.Tensor:
|
||||
inputs = self.fake_context_parallel_forward(inputs)
|
||||
|
||||
self._clear_fake_context_parallel_cache()
|
||||
# Note: we could move these to the cpu for a lower maximum memory usage but its only a few
|
||||
# hundred megabytes and so let's not do it for now
|
||||
self.conv_cache = inputs[:, :, -self.time_kernel_size + 1 :].clone()
|
||||
|
||||
padding_2d = (self.width_pad, self.width_pad, self.height_pad, self.height_pad)
|
||||
inputs = F.pad(inputs, padding_2d, mode="constant", value=0)
|
||||
|
||||
output = self.conv(inputs)
|
||||
return output, conv_cache
|
||||
return output
|
||||
|
||||
|
||||
class CogVideoXSpatialNorm3D(nn.Module):
|
||||
@@ -174,12 +172,7 @@ class CogVideoXSpatialNorm3D(nn.Module):
|
||||
self.conv_y = CogVideoXCausalConv3d(zq_channels, f_channels, kernel_size=1, stride=1)
|
||||
self.conv_b = CogVideoXCausalConv3d(zq_channels, f_channels, kernel_size=1, stride=1)
|
||||
|
||||
def forward(
|
||||
self, f: torch.Tensor, zq: torch.Tensor, conv_cache: Optional[Dict[str, torch.Tensor]] = None
|
||||
) -> torch.Tensor:
|
||||
new_conv_cache = {}
|
||||
conv_cache = conv_cache or {}
|
||||
|
||||
def forward(self, f: torch.Tensor, zq: torch.Tensor) -> torch.Tensor:
|
||||
if f.shape[2] > 1 and f.shape[2] % 2 == 1:
|
||||
f_first, f_rest = f[:, :, :1], f[:, :, 1:]
|
||||
f_first_size, f_rest_size = f_first.shape[-3:], f_rest.shape[-3:]
|
||||
@@ -190,87 +183,9 @@ class CogVideoXSpatialNorm3D(nn.Module):
|
||||
else:
|
||||
zq = F.interpolate(zq, size=f.shape[-3:])
|
||||
|
||||
conv_y, new_conv_cache["conv_y"] = self.conv_y(zq, conv_cache=conv_cache.get("conv_y"))
|
||||
conv_b, new_conv_cache["conv_b"] = self.conv_b(zq, conv_cache=conv_cache.get("conv_b"))
|
||||
|
||||
norm_f = self.norm_layer(f)
|
||||
new_f = norm_f * conv_y + conv_b
|
||||
return new_f, new_conv_cache
|
||||
|
||||
|
||||
class CogVideoXUpsample3D(nn.Module):
|
||||
r"""
|
||||
A 3D Upsample layer using in CogVideoX by Tsinghua University & ZhipuAI # Todo: Wait for paper relase.
|
||||
|
||||
Args:
|
||||
in_channels (`int`):
|
||||
Number of channels in the input image.
|
||||
out_channels (`int`):
|
||||
Number of channels produced by the convolution.
|
||||
kernel_size (`int`, defaults to `3`):
|
||||
Size of the convolving kernel.
|
||||
stride (`int`, defaults to `1`):
|
||||
Stride of the convolution.
|
||||
padding (`int`, defaults to `1`):
|
||||
Padding added to all four sides of the input.
|
||||
compress_time (`bool`, defaults to `False`):
|
||||
Whether or not to compress the time dimension.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
in_channels: int,
|
||||
out_channels: int,
|
||||
kernel_size: int = 3,
|
||||
stride: int = 1,
|
||||
padding: int = 1,
|
||||
compress_time: bool = False,
|
||||
) -> None:
|
||||
super().__init__()
|
||||
|
||||
self.conv = nn.Conv2d(in_channels, out_channels, kernel_size=kernel_size, stride=stride, padding=padding)
|
||||
self.compress_time = compress_time
|
||||
|
||||
self.auto_split_process = True
|
||||
self.first_frame_flag = False
|
||||
|
||||
def forward(self, inputs: torch.Tensor) -> torch.Tensor:
|
||||
if self.compress_time:
|
||||
if self.auto_split_process:
|
||||
if inputs.shape[2] > 1 and inputs.shape[2] % 2 == 1:
|
||||
# split first frame
|
||||
x_first, x_rest = inputs[:, :, 0], inputs[:, :, 1:]
|
||||
|
||||
x_first = F.interpolate(x_first, scale_factor=2.0)
|
||||
x_rest = F.interpolate(x_rest, scale_factor=2.0)
|
||||
x_first = x_first[:, :, None, :, :]
|
||||
inputs = torch.cat([x_first, x_rest], dim=2)
|
||||
elif inputs.shape[2] > 1:
|
||||
inputs = F.interpolate(inputs, scale_factor=2.0)
|
||||
else:
|
||||
inputs = inputs.squeeze(2)
|
||||
inputs = F.interpolate(inputs, scale_factor=2.0)
|
||||
inputs = inputs[:, :, None, :, :]
|
||||
else:
|
||||
if self.first_frame_flag:
|
||||
inputs = inputs.squeeze(2)
|
||||
inputs = F.interpolate(inputs, scale_factor=2.0)
|
||||
inputs = inputs[:, :, None, :, :]
|
||||
else:
|
||||
inputs = F.interpolate(inputs, scale_factor=2.0)
|
||||
else:
|
||||
# only interpolate 2D
|
||||
b, c, t, h, w = inputs.shape
|
||||
inputs = inputs.permute(0, 2, 1, 3, 4).reshape(b * t, c, h, w)
|
||||
inputs = F.interpolate(inputs, scale_factor=2.0)
|
||||
inputs = inputs.reshape(b, t, c, *inputs.shape[2:]).permute(0, 2, 1, 3, 4)
|
||||
|
||||
b, c, t, h, w = inputs.shape
|
||||
inputs = inputs.permute(0, 2, 1, 3, 4).reshape(b * t, c, h, w)
|
||||
inputs = self.conv(inputs)
|
||||
inputs = inputs.reshape(b, t, *inputs.shape[1:]).permute(0, 2, 1, 3, 4)
|
||||
|
||||
return inputs
|
||||
new_f = norm_f * self.conv_y(zq) + self.conv_b(zq)
|
||||
return new_f
|
||||
|
||||
|
||||
class CogVideoXResnetBlock3D(nn.Module):
|
||||
@@ -321,7 +236,6 @@ class CogVideoXResnetBlock3D(nn.Module):
|
||||
self.out_channels = out_channels
|
||||
self.nonlinearity = get_activation(non_linearity)
|
||||
self.use_conv_shortcut = conv_shortcut
|
||||
self.spatial_norm_dim = spatial_norm_dim
|
||||
|
||||
if spatial_norm_dim is None:
|
||||
self.norm1 = nn.GroupNorm(num_channels=in_channels, num_groups=groups, eps=eps)
|
||||
@@ -365,43 +279,34 @@ class CogVideoXResnetBlock3D(nn.Module):
|
||||
inputs: torch.Tensor,
|
||||
temb: Optional[torch.Tensor] = None,
|
||||
zq: Optional[torch.Tensor] = None,
|
||||
conv_cache: Optional[Dict[str, torch.Tensor]] = None,
|
||||
) -> torch.Tensor:
|
||||
new_conv_cache = {}
|
||||
conv_cache = conv_cache or {}
|
||||
|
||||
hidden_states = inputs
|
||||
|
||||
if zq is not None:
|
||||
hidden_states, new_conv_cache["norm1"] = self.norm1(hidden_states, zq, conv_cache=conv_cache.get("norm1"))
|
||||
hidden_states = self.norm1(hidden_states, zq)
|
||||
else:
|
||||
hidden_states = self.norm1(hidden_states)
|
||||
|
||||
hidden_states = self.nonlinearity(hidden_states)
|
||||
hidden_states, new_conv_cache["conv1"] = self.conv1(hidden_states, conv_cache=conv_cache.get("conv1"))
|
||||
hidden_states = self.conv1(hidden_states)
|
||||
|
||||
if temb is not None:
|
||||
hidden_states = hidden_states + self.temb_proj(self.nonlinearity(temb))[:, :, None, None, None]
|
||||
|
||||
if zq is not None:
|
||||
hidden_states, new_conv_cache["norm2"] = self.norm2(hidden_states, zq, conv_cache=conv_cache.get("norm2"))
|
||||
hidden_states = self.norm2(hidden_states, zq)
|
||||
else:
|
||||
hidden_states = self.norm2(hidden_states)
|
||||
|
||||
hidden_states = self.nonlinearity(hidden_states)
|
||||
hidden_states = self.dropout(hidden_states)
|
||||
hidden_states, new_conv_cache["conv2"] = self.conv2(hidden_states, conv_cache=conv_cache.get("conv2"))
|
||||
hidden_states = self.conv2(hidden_states)
|
||||
|
||||
if self.in_channels != self.out_channels:
|
||||
if self.use_conv_shortcut:
|
||||
inputs, new_conv_cache["conv_shortcut"] = self.conv_shortcut(
|
||||
inputs, conv_cache=conv_cache.get("conv_shortcut")
|
||||
)
|
||||
else:
|
||||
inputs = self.conv_shortcut(inputs)
|
||||
inputs = self.conv_shortcut(inputs)
|
||||
|
||||
hidden_states = hidden_states + inputs
|
||||
return hidden_states, new_conv_cache
|
||||
return hidden_states
|
||||
|
||||
|
||||
class CogVideoXDownBlock3D(nn.Module):
|
||||
@@ -487,17 +392,9 @@ class CogVideoXDownBlock3D(nn.Module):
|
||||
hidden_states: torch.Tensor,
|
||||
temb: Optional[torch.Tensor] = None,
|
||||
zq: Optional[torch.Tensor] = None,
|
||||
conv_cache: Optional[Dict[str, torch.Tensor]] = None,
|
||||
) -> torch.Tensor:
|
||||
r"""Forward method of the `CogVideoXDownBlock3D` class."""
|
||||
|
||||
new_conv_cache = {}
|
||||
conv_cache = conv_cache or {}
|
||||
|
||||
for i, resnet in enumerate(self.resnets):
|
||||
conv_cache_key = f"resnet_{i}"
|
||||
|
||||
if torch.is_grad_enabled() and self.gradient_checkpointing:
|
||||
for resnet in self.resnets:
|
||||
if self.training and self.gradient_checkpointing:
|
||||
|
||||
def create_custom_forward(module):
|
||||
def create_forward(*inputs):
|
||||
@@ -505,23 +402,17 @@ class CogVideoXDownBlock3D(nn.Module):
|
||||
|
||||
return create_forward
|
||||
|
||||
hidden_states, new_conv_cache[conv_cache_key] = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(resnet),
|
||||
hidden_states,
|
||||
temb,
|
||||
zq,
|
||||
conv_cache.get(conv_cache_key),
|
||||
hidden_states = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(resnet), hidden_states, temb, zq
|
||||
)
|
||||
else:
|
||||
hidden_states, new_conv_cache[conv_cache_key] = resnet(
|
||||
hidden_states, temb, zq, conv_cache=conv_cache.get(conv_cache_key)
|
||||
)
|
||||
hidden_states = resnet(hidden_states, temb, zq)
|
||||
|
||||
if self.downsamplers is not None:
|
||||
for downsampler in self.downsamplers:
|
||||
hidden_states = downsampler(hidden_states)
|
||||
|
||||
return hidden_states, new_conv_cache
|
||||
return hidden_states
|
||||
|
||||
|
||||
class CogVideoXMidBlock3D(nn.Module):
|
||||
@@ -589,17 +480,9 @@ class CogVideoXMidBlock3D(nn.Module):
|
||||
hidden_states: torch.Tensor,
|
||||
temb: Optional[torch.Tensor] = None,
|
||||
zq: Optional[torch.Tensor] = None,
|
||||
conv_cache: Optional[Dict[str, torch.Tensor]] = None,
|
||||
) -> torch.Tensor:
|
||||
r"""Forward method of the `CogVideoXMidBlock3D` class."""
|
||||
|
||||
new_conv_cache = {}
|
||||
conv_cache = conv_cache or {}
|
||||
|
||||
for i, resnet in enumerate(self.resnets):
|
||||
conv_cache_key = f"resnet_{i}"
|
||||
|
||||
if torch.is_grad_enabled() and self.gradient_checkpointing:
|
||||
for resnet in self.resnets:
|
||||
if self.training and self.gradient_checkpointing:
|
||||
|
||||
def create_custom_forward(module):
|
||||
def create_forward(*inputs):
|
||||
@@ -607,15 +490,13 @@ class CogVideoXMidBlock3D(nn.Module):
|
||||
|
||||
return create_forward
|
||||
|
||||
hidden_states, new_conv_cache[conv_cache_key] = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(resnet), hidden_states, temb, zq, conv_cache.get(conv_cache_key)
|
||||
hidden_states = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(resnet), hidden_states, temb, zq
|
||||
)
|
||||
else:
|
||||
hidden_states, new_conv_cache[conv_cache_key] = resnet(
|
||||
hidden_states, temb, zq, conv_cache=conv_cache.get(conv_cache_key)
|
||||
)
|
||||
hidden_states = resnet(hidden_states, temb, zq)
|
||||
|
||||
return hidden_states, new_conv_cache
|
||||
return hidden_states
|
||||
|
||||
|
||||
class CogVideoXUpBlock3D(nn.Module):
|
||||
@@ -703,17 +584,10 @@ class CogVideoXUpBlock3D(nn.Module):
|
||||
hidden_states: torch.Tensor,
|
||||
temb: Optional[torch.Tensor] = None,
|
||||
zq: Optional[torch.Tensor] = None,
|
||||
conv_cache: Optional[Dict[str, torch.Tensor]] = None,
|
||||
) -> torch.Tensor:
|
||||
r"""Forward method of the `CogVideoXUpBlock3D` class."""
|
||||
|
||||
new_conv_cache = {}
|
||||
conv_cache = conv_cache or {}
|
||||
|
||||
for i, resnet in enumerate(self.resnets):
|
||||
conv_cache_key = f"resnet_{i}"
|
||||
|
||||
if torch.is_grad_enabled() and self.gradient_checkpointing:
|
||||
for resnet in self.resnets:
|
||||
if self.training and self.gradient_checkpointing:
|
||||
|
||||
def create_custom_forward(module):
|
||||
def create_forward(*inputs):
|
||||
@@ -721,23 +595,17 @@ class CogVideoXUpBlock3D(nn.Module):
|
||||
|
||||
return create_forward
|
||||
|
||||
hidden_states, new_conv_cache[conv_cache_key] = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(resnet),
|
||||
hidden_states,
|
||||
temb,
|
||||
zq,
|
||||
conv_cache.get(conv_cache_key),
|
||||
hidden_states = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(resnet), hidden_states, temb, zq
|
||||
)
|
||||
else:
|
||||
hidden_states, new_conv_cache[conv_cache_key] = resnet(
|
||||
hidden_states, temb, zq, conv_cache=conv_cache.get(conv_cache_key)
|
||||
)
|
||||
hidden_states = resnet(hidden_states, temb, zq)
|
||||
|
||||
if self.upsamplers is not None:
|
||||
for upsampler in self.upsamplers:
|
||||
hidden_states = upsampler(hidden_states)
|
||||
|
||||
return hidden_states, new_conv_cache
|
||||
return hidden_states
|
||||
|
||||
|
||||
class CogVideoXEncoder3D(nn.Module):
|
||||
@@ -837,20 +705,11 @@ class CogVideoXEncoder3D(nn.Module):
|
||||
|
||||
self.gradient_checkpointing = False
|
||||
|
||||
def forward(
|
||||
self,
|
||||
sample: torch.Tensor,
|
||||
temb: Optional[torch.Tensor] = None,
|
||||
conv_cache: Optional[Dict[str, torch.Tensor]] = None,
|
||||
) -> torch.Tensor:
|
||||
def forward(self, sample: torch.Tensor, temb: Optional[torch.Tensor] = None) -> torch.Tensor:
|
||||
r"""The forward method of the `CogVideoXEncoder3D` class."""
|
||||
hidden_states = self.conv_in(sample)
|
||||
|
||||
new_conv_cache = {}
|
||||
conv_cache = conv_cache or {}
|
||||
|
||||
hidden_states, new_conv_cache["conv_in"] = self.conv_in(sample, conv_cache=conv_cache.get("conv_in"))
|
||||
|
||||
if torch.is_grad_enabled() and self.gradient_checkpointing:
|
||||
if self.training and self.gradient_checkpointing:
|
||||
|
||||
def create_custom_forward(module):
|
||||
def custom_forward(*inputs):
|
||||
@@ -859,44 +718,28 @@ class CogVideoXEncoder3D(nn.Module):
|
||||
return custom_forward
|
||||
|
||||
# 1. Down
|
||||
for i, down_block in enumerate(self.down_blocks):
|
||||
conv_cache_key = f"down_block_{i}"
|
||||
hidden_states, new_conv_cache[conv_cache_key] = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(down_block),
|
||||
hidden_states,
|
||||
temb,
|
||||
None,
|
||||
conv_cache.get(conv_cache_key),
|
||||
for down_block in self.down_blocks:
|
||||
hidden_states = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(down_block), hidden_states, temb, None
|
||||
)
|
||||
|
||||
# 2. Mid
|
||||
hidden_states, new_conv_cache["mid_block"] = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(self.mid_block),
|
||||
hidden_states,
|
||||
temb,
|
||||
None,
|
||||
conv_cache.get("mid_block"),
|
||||
hidden_states = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(self.mid_block), hidden_states, temb, None
|
||||
)
|
||||
else:
|
||||
# 1. Down
|
||||
for i, down_block in enumerate(self.down_blocks):
|
||||
conv_cache_key = f"down_block_{i}"
|
||||
hidden_states, new_conv_cache[conv_cache_key] = down_block(
|
||||
hidden_states, temb, None, conv_cache=conv_cache.get(conv_cache_key)
|
||||
)
|
||||
for down_block in self.down_blocks:
|
||||
hidden_states = down_block(hidden_states, temb, None)
|
||||
|
||||
# 2. Mid
|
||||
hidden_states, new_conv_cache["mid_block"] = self.mid_block(
|
||||
hidden_states, temb, None, conv_cache=conv_cache.get("mid_block")
|
||||
)
|
||||
hidden_states = self.mid_block(hidden_states, temb, None)
|
||||
|
||||
# 3. Post-process
|
||||
hidden_states = self.norm_out(hidden_states)
|
||||
hidden_states = self.conv_act(hidden_states)
|
||||
|
||||
hidden_states, new_conv_cache["conv_out"] = self.conv_out(hidden_states, conv_cache=conv_cache.get("conv_out"))
|
||||
|
||||
return hidden_states, new_conv_cache
|
||||
hidden_states = self.conv_out(hidden_states)
|
||||
return hidden_states
|
||||
|
||||
|
||||
class CogVideoXDecoder3D(nn.Module):
|
||||
@@ -1003,20 +846,11 @@ class CogVideoXDecoder3D(nn.Module):
|
||||
|
||||
self.gradient_checkpointing = False
|
||||
|
||||
def forward(
|
||||
self,
|
||||
sample: torch.Tensor,
|
||||
temb: Optional[torch.Tensor] = None,
|
||||
conv_cache: Optional[Dict[str, torch.Tensor]] = None,
|
||||
) -> torch.Tensor:
|
||||
def forward(self, sample: torch.Tensor, temb: Optional[torch.Tensor] = None) -> torch.Tensor:
|
||||
r"""The forward method of the `CogVideoXDecoder3D` class."""
|
||||
hidden_states = self.conv_in(sample)
|
||||
|
||||
new_conv_cache = {}
|
||||
conv_cache = conv_cache or {}
|
||||
|
||||
hidden_states, new_conv_cache["conv_in"] = self.conv_in(sample, conv_cache=conv_cache.get("conv_in"))
|
||||
|
||||
if torch.is_grad_enabled() and self.gradient_checkpointing:
|
||||
if self.training and self.gradient_checkpointing:
|
||||
|
||||
def create_custom_forward(module):
|
||||
def custom_forward(*inputs):
|
||||
@@ -1025,45 +859,28 @@ class CogVideoXDecoder3D(nn.Module):
|
||||
return custom_forward
|
||||
|
||||
# 1. Mid
|
||||
hidden_states, new_conv_cache["mid_block"] = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(self.mid_block),
|
||||
hidden_states,
|
||||
temb,
|
||||
sample,
|
||||
conv_cache.get("mid_block"),
|
||||
hidden_states = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(self.mid_block), hidden_states, temb, sample
|
||||
)
|
||||
|
||||
# 2. Up
|
||||
for i, up_block in enumerate(self.up_blocks):
|
||||
conv_cache_key = f"up_block_{i}"
|
||||
hidden_states, new_conv_cache[conv_cache_key] = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(up_block),
|
||||
hidden_states,
|
||||
temb,
|
||||
sample,
|
||||
conv_cache.get(conv_cache_key),
|
||||
for up_block in self.up_blocks:
|
||||
hidden_states = torch.utils.checkpoint.checkpoint(
|
||||
create_custom_forward(up_block), hidden_states, temb, sample
|
||||
)
|
||||
else:
|
||||
# 1. Mid
|
||||
hidden_states, new_conv_cache["mid_block"] = self.mid_block(
|
||||
hidden_states, temb, sample, conv_cache=conv_cache.get("mid_block")
|
||||
)
|
||||
hidden_states = self.mid_block(hidden_states, temb, sample)
|
||||
|
||||
# 2. Up
|
||||
for i, up_block in enumerate(self.up_blocks):
|
||||
conv_cache_key = f"up_block_{i}"
|
||||
hidden_states, new_conv_cache[conv_cache_key] = up_block(
|
||||
hidden_states, temb, sample, conv_cache=conv_cache.get(conv_cache_key)
|
||||
)
|
||||
for up_block in self.up_blocks:
|
||||
hidden_states = up_block(hidden_states, temb, sample)
|
||||
|
||||
# 3. Post-process
|
||||
hidden_states, new_conv_cache["norm_out"] = self.norm_out(
|
||||
hidden_states, sample, conv_cache=conv_cache.get("norm_out")
|
||||
)
|
||||
hidden_states = self.norm_out(hidden_states, sample)
|
||||
hidden_states = self.conv_act(hidden_states)
|
||||
hidden_states, new_conv_cache["conv_out"] = self.conv_out(hidden_states, conv_cache=conv_cache.get("conv_out"))
|
||||
|
||||
return hidden_states, new_conv_cache
|
||||
hidden_states = self.conv_out(hidden_states)
|
||||
return hidden_states
|
||||
|
||||
|
||||
class AutoencoderKLCogVideoX(ModelMixin, ConfigMixin, FromOriginalModelMixin):
|
||||
@@ -1134,7 +951,6 @@ class AutoencoderKLCogVideoX(ModelMixin, ConfigMixin, FromOriginalModelMixin):
|
||||
force_upcast: float = True,
|
||||
use_quant_conv: bool = False,
|
||||
use_post_quant_conv: bool = False,
|
||||
invert_scale_latents: bool = False,
|
||||
):
|
||||
super().__init__()
|
||||
|
||||
@@ -1165,7 +981,6 @@ class AutoencoderKLCogVideoX(ModelMixin, ConfigMixin, FromOriginalModelMixin):
|
||||
|
||||
self.use_slicing = False
|
||||
self.use_tiling = False
|
||||
self.auto_split_process = False
|
||||
|
||||
# Can be increased to decode more latent frames at once, but comes at a reasonable memory cost and it is not
|
||||
# recommended because the temporal parts of the VAE, here, are tricky to understand.
|
||||
@@ -1184,7 +999,6 @@ class AutoencoderKLCogVideoX(ModelMixin, ConfigMixin, FromOriginalModelMixin):
|
||||
# setting it to anything other than 2 would give poor results because the VAE hasn't been trained to be adaptive with different
|
||||
# number of temporal frames.
|
||||
self.num_latent_frames_batch_size = 2
|
||||
self.num_sample_frames_batch_size = 8
|
||||
|
||||
# We make the minimum height and width of sample for tiling half that of the generally supported
|
||||
self.tile_sample_min_height = sample_height // 2
|
||||
@@ -1204,6 +1018,12 @@ class AutoencoderKLCogVideoX(ModelMixin, ConfigMixin, FromOriginalModelMixin):
|
||||
if isinstance(module, (CogVideoXEncoder3D, CogVideoXDecoder3D)):
|
||||
module.gradient_checkpointing = value
|
||||
|
||||
def _clear_fake_context_parallel_cache(self):
|
||||
for name, module in self.named_modules():
|
||||
if isinstance(module, CogVideoXCausalConv3d):
|
||||
logger.debug(f"Clearing fake Context Parallel cache for layer: {name}")
|
||||
module._clear_fake_context_parallel_cache()
|
||||
|
||||
def enable_tiling(
|
||||
self,
|
||||
tile_sample_min_height: Optional[int] = None,
|
||||
@@ -1260,53 +1080,6 @@ class AutoencoderKLCogVideoX(ModelMixin, ConfigMixin, FromOriginalModelMixin):
|
||||
decoding in one step.
|
||||
"""
|
||||
self.use_slicing = False
|
||||
|
||||
def _set_first_frame(self):
|
||||
for name, module in self.named_modules():
|
||||
if isinstance(module, CogVideoXUpsample3D):
|
||||
module.auto_split_process = False
|
||||
module.first_frame_flag = True
|
||||
|
||||
def _set_rest_frame(self):
|
||||
for name, module in self.named_modules():
|
||||
if isinstance(module, CogVideoXUpsample3D):
|
||||
module.auto_split_process = False
|
||||
module.first_frame_flag = False
|
||||
|
||||
def enable_auto_split_process(self) -> None:
|
||||
self.auto_split_process = True
|
||||
for name, module in self.named_modules():
|
||||
if isinstance(module, CogVideoXUpsample3D):
|
||||
module.auto_split_process = True
|
||||
|
||||
def disable_auto_split_process(self) -> None:
|
||||
self.auto_split_process = False
|
||||
|
||||
def _encode(self, x: torch.Tensor) -> torch.Tensor:
|
||||
batch_size, num_channels, num_frames, height, width = x.shape
|
||||
|
||||
if self.use_tiling and (width > self.tile_sample_min_width or height > self.tile_sample_min_height):
|
||||
return self.tiled_encode(x)
|
||||
|
||||
frame_batch_size = self.num_sample_frames_batch_size
|
||||
# Note: We expect the number of frames to be either `1` or `frame_batch_size * k` or `frame_batch_size * k + 1` for some k.
|
||||
# As the extra single frame is handled inside the loop, it is not required to round up here.
|
||||
num_batches = max(num_frames // frame_batch_size, 1)
|
||||
conv_cache = None
|
||||
enc = []
|
||||
|
||||
for i in range(num_batches):
|
||||
remaining_frames = num_frames % frame_batch_size
|
||||
start_frame = frame_batch_size * i + (0 if i == 0 else remaining_frames)
|
||||
end_frame = frame_batch_size * (i + 1) + remaining_frames
|
||||
x_intermediate = x[:, :, start_frame:end_frame]
|
||||
x_intermediate, conv_cache = self.encoder(x_intermediate, conv_cache=conv_cache)
|
||||
if self.quant_conv is not None:
|
||||
x_intermediate = self.quant_conv(x_intermediate)
|
||||
enc.append(x_intermediate)
|
||||
|
||||
enc = torch.cat(enc, dim=2)
|
||||
return enc
|
||||
|
||||
@apply_forward_hook
|
||||
def encode(
|
||||
@@ -1321,17 +1094,30 @@ class AutoencoderKLCogVideoX(ModelMixin, ConfigMixin, FromOriginalModelMixin):
|
||||
Whether to return a [`~models.autoencoder_kl.AutoencoderKLOutput`] instead of a plain tuple.
|
||||
|
||||
Returns:
|
||||
The latent representations of the encoded videos. If `return_dict` is True, a
|
||||
The latent representations of the encoded images. If `return_dict` is True, a
|
||||
[`~models.autoencoder_kl.AutoencoderKLOutput`] is returned, otherwise a plain `tuple` is returned.
|
||||
"""
|
||||
if self.use_slicing and x.shape[0] > 1:
|
||||
encoded_slices = [self._encode(x_slice) for x_slice in x.split(1)]
|
||||
h = torch.cat(encoded_slices)
|
||||
batch_size, num_channels, num_frames, height, width = x.shape
|
||||
if num_frames == 1:
|
||||
h = self.encoder(x)
|
||||
if self.quant_conv is not None:
|
||||
h = self.quant_conv(h)
|
||||
posterior = DiagonalGaussianDistribution(h)
|
||||
else:
|
||||
h = self._encode(x)
|
||||
|
||||
posterior = DiagonalGaussianDistribution(h)
|
||||
|
||||
frame_batch_size = 4
|
||||
h = []
|
||||
for i in range(num_frames // frame_batch_size):
|
||||
remaining_frames = num_frames % frame_batch_size
|
||||
start_frame = frame_batch_size * i + (0 if i == 0 else remaining_frames)
|
||||
end_frame = frame_batch_size * (i + 1) + remaining_frames
|
||||
z_intermediate = x[:, :, start_frame:end_frame]
|
||||
z_intermediate = self.encoder(z_intermediate)
|
||||
if self.quant_conv is not None:
|
||||
z_intermediate = self.quant_conv(z_intermediate)
|
||||
h.append(z_intermediate)
|
||||
self._clear_fake_context_parallel_cache()
|
||||
h = torch.cat(h, dim=2)
|
||||
posterior = DiagonalGaussianDistribution(h)
|
||||
if not return_dict:
|
||||
return (posterior,)
|
||||
return AutoencoderKLOutput(latent_dist=posterior)
|
||||
@@ -1342,47 +1128,27 @@ class AutoencoderKLCogVideoX(ModelMixin, ConfigMixin, FromOriginalModelMixin):
|
||||
if self.use_tiling and (width > self.tile_latent_min_width or height > self.tile_latent_min_height):
|
||||
return self.tiled_decode(z, return_dict=return_dict)
|
||||
|
||||
if self.auto_split_process:
|
||||
frame_batch_size = self.num_latent_frames_batch_size
|
||||
num_batches = max(num_frames // frame_batch_size, 1)
|
||||
conv_cache = None
|
||||
if num_frames == 1:
|
||||
dec = []
|
||||
|
||||
for i in range(num_batches):
|
||||
z_intermediate = z
|
||||
if self.post_quant_conv is not None:
|
||||
z_intermediate = self.post_quant_conv(z_intermediate)
|
||||
z_intermediate = self.decoder(z_intermediate)
|
||||
dec.append(z_intermediate)
|
||||
else:
|
||||
frame_batch_size = self.num_latent_frames_batch_size
|
||||
dec = []
|
||||
for i in range(num_frames // frame_batch_size):
|
||||
remaining_frames = num_frames % frame_batch_size
|
||||
start_frame = frame_batch_size * i + (0 if i == 0 else remaining_frames)
|
||||
end_frame = frame_batch_size * (i + 1) + remaining_frames
|
||||
z_intermediate = z[:, :, start_frame:end_frame]
|
||||
if self.post_quant_conv is not None:
|
||||
z_intermediate = self.post_quant_conv(z_intermediate)
|
||||
z_intermediate, conv_cache = self.decoder(z_intermediate, conv_cache=conv_cache)
|
||||
z_intermediate = self.decoder(z_intermediate)
|
||||
dec.append(z_intermediate)
|
||||
else:
|
||||
conv_cache = None
|
||||
start_frame = 0
|
||||
end_frame = 1
|
||||
dec = []
|
||||
|
||||
self._set_first_frame()
|
||||
z_intermediate = z[:, :, start_frame:end_frame]
|
||||
if self.post_quant_conv is not None:
|
||||
z_intermediate = self.post_quant_conv(z_intermediate)
|
||||
z_intermediate, conv_cache = self.decoder(z_intermediate, conv_cache=conv_cache)
|
||||
dec.append(z_intermediate)
|
||||
|
||||
self._set_rest_frame()
|
||||
start_frame = end_frame
|
||||
end_frame += self.num_latent_frames_batch_size
|
||||
|
||||
while start_frame < num_frames:
|
||||
z_intermediate = z[:, :, start_frame:end_frame]
|
||||
if self.post_quant_conv is not None:
|
||||
z_intermediate = self.post_quant_conv(z_intermediate)
|
||||
z_intermediate, conv_cache = self.decoder(z_intermediate, conv_cache=conv_cache)
|
||||
dec.append(z_intermediate)
|
||||
start_frame = end_frame
|
||||
end_frame += self.num_latent_frames_batch_size
|
||||
|
||||
self._clear_fake_context_parallel_cache()
|
||||
dec = torch.cat(dec, dim=2)
|
||||
|
||||
if not return_dict:
|
||||
@@ -1431,80 +1197,6 @@ class AutoencoderKLCogVideoX(ModelMixin, ConfigMixin, FromOriginalModelMixin):
|
||||
)
|
||||
return b
|
||||
|
||||
def tiled_encode(self, x: torch.Tensor) -> torch.Tensor:
|
||||
r"""Encode a batch of images using a tiled encoder.
|
||||
|
||||
When this option is enabled, the VAE will split the input tensor into tiles to compute encoding in several
|
||||
steps. This is useful to keep memory use constant regardless of image size. The end result of tiled encoding is
|
||||
different from non-tiled encoding because each tile uses a different encoder. To avoid tiling artifacts, the
|
||||
tiles overlap and are blended together to form a smooth output. You may still see tile-sized changes in the
|
||||
output, but they should be much less noticeable.
|
||||
|
||||
Args:
|
||||
x (`torch.Tensor`): Input batch of videos.
|
||||
|
||||
Returns:
|
||||
`torch.Tensor`:
|
||||
The latent representation of the encoded videos.
|
||||
"""
|
||||
# For a rough memory estimate, take a look at the `tiled_decode` method.
|
||||
batch_size, num_channels, num_frames, height, width = x.shape
|
||||
|
||||
overlap_height = int(self.tile_sample_min_height * (1 - self.tile_overlap_factor_height))
|
||||
overlap_width = int(self.tile_sample_min_width * (1 - self.tile_overlap_factor_width))
|
||||
blend_extent_height = int(self.tile_latent_min_height * self.tile_overlap_factor_height)
|
||||
blend_extent_width = int(self.tile_latent_min_width * self.tile_overlap_factor_width)
|
||||
row_limit_height = self.tile_latent_min_height - blend_extent_height
|
||||
row_limit_width = self.tile_latent_min_width - blend_extent_width
|
||||
frame_batch_size = self.num_sample_frames_batch_size
|
||||
|
||||
# Split x into overlapping tiles and encode them separately.
|
||||
# The tiles have an overlap to avoid seams between tiles.
|
||||
rows = []
|
||||
for i in range(0, height, overlap_height):
|
||||
row = []
|
||||
for j in range(0, width, overlap_width):
|
||||
# Note: We expect the number of frames to be either `1` or `frame_batch_size * k` or `frame_batch_size * k + 1` for some k.
|
||||
# As the extra single frame is handled inside the loop, it is not required to round up here.
|
||||
num_batches = max(num_frames // frame_batch_size, 1)
|
||||
conv_cache = None
|
||||
time = []
|
||||
|
||||
for k in range(num_batches):
|
||||
remaining_frames = num_frames % frame_batch_size
|
||||
start_frame = frame_batch_size * k + (0 if k == 0 else remaining_frames)
|
||||
end_frame = frame_batch_size * (k + 1) + remaining_frames
|
||||
tile = x[
|
||||
:,
|
||||
:,
|
||||
start_frame:end_frame,
|
||||
i : i + self.tile_sample_min_height,
|
||||
j : j + self.tile_sample_min_width,
|
||||
]
|
||||
tile, conv_cache = self.encoder(tile, conv_cache=conv_cache)
|
||||
if self.quant_conv is not None:
|
||||
tile = self.quant_conv(tile)
|
||||
time.append(tile)
|
||||
|
||||
row.append(torch.cat(time, dim=2))
|
||||
rows.append(row)
|
||||
|
||||
result_rows = []
|
||||
for i, row in enumerate(rows):
|
||||
result_row = []
|
||||
for j, tile in enumerate(row):
|
||||
# blend the above tile and the left tile
|
||||
# to the current tile and add the current tile to the result row
|
||||
if i > 0:
|
||||
tile = self.blend_v(rows[i - 1][j], tile, blend_extent_height)
|
||||
if j > 0:
|
||||
tile = self.blend_h(row[j - 1], tile, blend_extent_width)
|
||||
result_row.append(tile[:, :, :, :row_limit_height, :row_limit_width])
|
||||
result_rows.append(torch.cat(result_row, dim=4))
|
||||
|
||||
enc = torch.cat(result_rows, dim=3)
|
||||
return enc
|
||||
|
||||
def tiled_decode(self, z: torch.Tensor, return_dict: bool = True) -> Union[DecoderOutput, torch.Tensor]:
|
||||
r"""
|
||||
Decode a batch of images using a tiled decoder.
|
||||
@@ -1545,34 +1237,11 @@ class AutoencoderKLCogVideoX(ModelMixin, ConfigMixin, FromOriginalModelMixin):
|
||||
for i in range(0, height, overlap_height):
|
||||
row = []
|
||||
for j in range(0, width, overlap_width):
|
||||
if self.auto_split_process:
|
||||
num_batches = max(num_frames // frame_batch_size, 1)
|
||||
conv_cache = None
|
||||
time = []
|
||||
|
||||
for k in range(num_batches):
|
||||
remaining_frames = num_frames % frame_batch_size
|
||||
start_frame = frame_batch_size * k + (0 if k == 0 else remaining_frames)
|
||||
end_frame = frame_batch_size * (k + 1) + remaining_frames
|
||||
tile = z[
|
||||
:,
|
||||
:,
|
||||
start_frame:end_frame,
|
||||
i : i + self.tile_latent_min_height,
|
||||
j : j + self.tile_latent_min_width,
|
||||
]
|
||||
if self.post_quant_conv is not None:
|
||||
tile = self.post_quant_conv(tile)
|
||||
tile, conv_cache = self.decoder(tile, conv_cache=conv_cache)
|
||||
time.append(tile)
|
||||
|
||||
row.append(torch.cat(time, dim=2))
|
||||
else:
|
||||
conv_cache = None
|
||||
start_frame = 0
|
||||
end_frame = 1
|
||||
dec = []
|
||||
|
||||
time = []
|
||||
for k in range(num_frames // frame_batch_size):
|
||||
remaining_frames = num_frames % frame_batch_size
|
||||
start_frame = frame_batch_size * k + (0 if k == 0 else remaining_frames)
|
||||
end_frame = frame_batch_size * (k + 1) + remaining_frames
|
||||
tile = z[
|
||||
:,
|
||||
:,
|
||||
@@ -1580,33 +1249,12 @@ class AutoencoderKLCogVideoX(ModelMixin, ConfigMixin, FromOriginalModelMixin):
|
||||
i : i + self.tile_latent_min_height,
|
||||
j : j + self.tile_latent_min_width,
|
||||
]
|
||||
|
||||
self._set_first_frame()
|
||||
if self.post_quant_conv is not None:
|
||||
tile = self.post_quant_conv(tile)
|
||||
tile, conv_cache = self.decoder(tile, conv_cache=conv_cache)
|
||||
dec.append(tile)
|
||||
|
||||
self._set_rest_frame()
|
||||
start_frame = end_frame
|
||||
end_frame += self.num_latent_frames_batch_size
|
||||
|
||||
while start_frame < num_frames:
|
||||
tile = z[
|
||||
:,
|
||||
:,
|
||||
start_frame:end_frame,
|
||||
i : i + self.tile_latent_min_height,
|
||||
j : j + self.tile_latent_min_width,
|
||||
]
|
||||
if self.post_quant_conv is not None:
|
||||
tile = self.post_quant_conv(tile)
|
||||
tile, conv_cache = self.decoder(tile, conv_cache=conv_cache)
|
||||
dec.append(tile)
|
||||
start_frame = end_frame
|
||||
end_frame += self.num_latent_frames_batch_size
|
||||
|
||||
row.append(torch.cat(dec, dim=2))
|
||||
tile = self.decoder(tile)
|
||||
time.append(tile)
|
||||
self._clear_fake_context_parallel_cache()
|
||||
row.append(torch.cat(time, dim=2))
|
||||
rows.append(row)
|
||||
|
||||
result_rows = []
|
||||
@@ -1646,30 +1294,3 @@ class AutoencoderKLCogVideoX(ModelMixin, ConfigMixin, FromOriginalModelMixin):
|
||||
if not return_dict:
|
||||
return (dec,)
|
||||
return dec
|
||||
|
||||
@classmethod
|
||||
def from_pretrained(cls, pretrained_model_path, subfolder=None, **vae_additional_kwargs):
|
||||
if subfolder is not None:
|
||||
pretrained_model_path = os.path.join(pretrained_model_path, subfolder)
|
||||
|
||||
config_file = os.path.join(pretrained_model_path, 'config.json')
|
||||
if not os.path.isfile(config_file):
|
||||
raise RuntimeError(f"{config_file} does not exist")
|
||||
with open(config_file, "r") as f:
|
||||
config = json.load(f)
|
||||
|
||||
model = cls.from_config(config, **vae_additional_kwargs)
|
||||
from diffusers.utils import WEIGHTS_NAME
|
||||
model_file = os.path.join(pretrained_model_path, WEIGHTS_NAME)
|
||||
model_file_safetensors = model_file.replace(".bin", ".safetensors")
|
||||
if os.path.exists(model_file_safetensors):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(model_file_safetensors)
|
||||
else:
|
||||
if not os.path.isfile(model_file):
|
||||
raise RuntimeError(f"{model_file} does not exist")
|
||||
state_dict = torch.load(model_file, map_location="cpu")
|
||||
m, u = model.load_state_dict(state_dict, strict=False)
|
||||
print(f"### missing keys: {len(m)}; \n### unexpected keys: {len(u)};")
|
||||
print(m, u)
|
||||
return model
|
||||
@@ -13,234 +13,29 @@
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import glob
|
||||
import json
|
||||
import os
|
||||
from typing import Any, Dict, Optional, Tuple, Union
|
||||
|
||||
import os
|
||||
import json
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from torch import nn
|
||||
|
||||
from diffusers.configuration_utils import ConfigMixin, register_to_config
|
||||
from diffusers.utils import is_torch_version, logging
|
||||
from diffusers.utils.torch_utils import maybe_allow_in_graph
|
||||
from diffusers.models.attention import Attention, FeedForward
|
||||
from diffusers.models.attention_processor import (
|
||||
AttentionProcessor, FusedCogVideoXAttnProcessor2_0)
|
||||
from diffusers.models.embeddings import (CogVideoXPatchEmbed,
|
||||
TimestepEmbedding, Timesteps,
|
||||
get_3d_sincos_pos_embed)
|
||||
from diffusers.models.attention_processor import AttentionProcessor, CogVideoXAttnProcessor2_0, FusedCogVideoXAttnProcessor2_0
|
||||
from diffusers.models.embeddings import CogVideoXPatchEmbed, TimestepEmbedding, Timesteps, get_3d_sincos_pos_embed
|
||||
from diffusers.models.modeling_outputs import Transformer2DModelOutput
|
||||
from diffusers.models.modeling_utils import ModelMixin
|
||||
from diffusers.models.normalization import AdaLayerNorm, CogVideoXLayerNormZero
|
||||
from diffusers.utils import is_torch_version, logging
|
||||
from diffusers.utils.torch_utils import maybe_allow_in_graph
|
||||
from torch import nn
|
||||
|
||||
from ..dist import (get_sequence_parallel_rank,
|
||||
get_sequence_parallel_world_size, get_sp_group,
|
||||
xFuserLongContextAttention)
|
||||
from ..dist.cogvideox_xfuser import CogVideoXMultiGPUsAttnProcessor2_0
|
||||
from .attention_utils import attention
|
||||
from cogvideox.models.attention_processor import CogVideoXSWAAttnProcessor2_0
|
||||
|
||||
|
||||
class CogVideoXAttnProcessor2_0:
|
||||
r"""
|
||||
Processor for implementing scaled dot-product attention for the CogVideoX model. It applies a rotary embedding on
|
||||
query and key vectors, but does not include spatial normalization.
|
||||
"""
|
||||
logger = logging.get_logger(__name__) # pylint: disable=invalid-name
|
||||
|
||||
def __init__(self):
|
||||
if not hasattr(F, "scaled_dot_product_attention"):
|
||||
raise ImportError("CogVideoXAttnProcessor requires PyTorch 2.0, to use it, please upgrade PyTorch to 2.0.")
|
||||
|
||||
def __call__(
|
||||
self,
|
||||
attn,
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: torch.Tensor,
|
||||
attention_mask: torch.Tensor = None,
|
||||
image_rotary_emb: torch.Tensor = None,
|
||||
) -> torch.Tensor:
|
||||
text_seq_length = encoder_hidden_states.size(1)
|
||||
|
||||
hidden_states = torch.cat([encoder_hidden_states, hidden_states], dim=1)
|
||||
|
||||
batch_size, sequence_length, _ = hidden_states.shape
|
||||
|
||||
if attention_mask is not None:
|
||||
attention_mask = attn.prepare_attention_mask(attention_mask, sequence_length, batch_size)
|
||||
attention_mask = attention_mask.view(batch_size, attn.heads, -1, attention_mask.shape[-1])
|
||||
|
||||
query = attn.to_q(hidden_states)
|
||||
key = attn.to_k(hidden_states)
|
||||
value = attn.to_v(hidden_states)
|
||||
|
||||
inner_dim = key.shape[-1]
|
||||
head_dim = inner_dim // attn.heads
|
||||
|
||||
query = query.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
key = key.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
value = value.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
if attn.norm_q is not None:
|
||||
query = attn.norm_q(query)
|
||||
if attn.norm_k is not None:
|
||||
key = attn.norm_k(key)
|
||||
|
||||
# Apply RoPE if needed
|
||||
if image_rotary_emb is not None:
|
||||
from diffusers.models.embeddings import apply_rotary_emb
|
||||
|
||||
query[:, :, text_seq_length:] = apply_rotary_emb(query[:, :, text_seq_length:], image_rotary_emb)
|
||||
if not attn.is_cross_attention:
|
||||
key[:, :, text_seq_length:] = apply_rotary_emb(key[:, :, text_seq_length:], image_rotary_emb)
|
||||
|
||||
query = query.transpose(1, 2)
|
||||
key = key.transpose(1, 2)
|
||||
value = value.transpose(1, 2)
|
||||
|
||||
hidden_states = attention(
|
||||
query, key, value, attn_mask=attention_mask, dropout_p=0.0, causal=False
|
||||
)
|
||||
hidden_states = hidden_states.reshape(batch_size, -1, attn.heads * head_dim)
|
||||
|
||||
# linear proj
|
||||
hidden_states = attn.to_out[0](hidden_states)
|
||||
# dropout
|
||||
hidden_states = attn.to_out[1](hidden_states)
|
||||
|
||||
encoder_hidden_states, hidden_states = hidden_states.split(
|
||||
[text_seq_length, hidden_states.size(1) - text_seq_length], dim=1
|
||||
)
|
||||
return hidden_states, encoder_hidden_states
|
||||
|
||||
|
||||
class CogVideoXPatchEmbed(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
patch_size: int = 2,
|
||||
patch_size_t: Optional[int] = None,
|
||||
in_channels: int = 16,
|
||||
embed_dim: int = 1920,
|
||||
text_embed_dim: int = 4096,
|
||||
bias: bool = True,
|
||||
sample_width: int = 90,
|
||||
sample_height: int = 60,
|
||||
sample_frames: int = 49,
|
||||
temporal_compression_ratio: int = 4,
|
||||
max_text_seq_length: int = 226,
|
||||
spatial_interpolation_scale: float = 1.875,
|
||||
temporal_interpolation_scale: float = 1.0,
|
||||
use_positional_embeddings: bool = True,
|
||||
use_learned_positional_embeddings: bool = True,
|
||||
) -> None:
|
||||
super().__init__()
|
||||
|
||||
post_patch_height = sample_height // patch_size
|
||||
post_patch_width = sample_width // patch_size
|
||||
post_time_compression_frames = (sample_frames - 1) // temporal_compression_ratio + 1
|
||||
self.num_patches = post_patch_height * post_patch_width * post_time_compression_frames
|
||||
self.post_patch_height = post_patch_height
|
||||
self.post_patch_width = post_patch_width
|
||||
self.post_time_compression_frames = post_time_compression_frames
|
||||
self.patch_size = patch_size
|
||||
self.patch_size_t = patch_size_t
|
||||
self.embed_dim = embed_dim
|
||||
self.sample_height = sample_height
|
||||
self.sample_width = sample_width
|
||||
self.sample_frames = sample_frames
|
||||
self.temporal_compression_ratio = temporal_compression_ratio
|
||||
self.max_text_seq_length = max_text_seq_length
|
||||
self.spatial_interpolation_scale = spatial_interpolation_scale
|
||||
self.temporal_interpolation_scale = temporal_interpolation_scale
|
||||
self.use_positional_embeddings = use_positional_embeddings
|
||||
self.use_learned_positional_embeddings = use_learned_positional_embeddings
|
||||
|
||||
if patch_size_t is None:
|
||||
# CogVideoX 1.0 checkpoints
|
||||
self.proj = nn.Conv2d(
|
||||
in_channels, embed_dim, kernel_size=(patch_size, patch_size), stride=patch_size, bias=bias
|
||||
)
|
||||
else:
|
||||
# CogVideoX 1.5 checkpoints
|
||||
self.proj = nn.Linear(in_channels * patch_size * patch_size * patch_size_t, embed_dim)
|
||||
|
||||
self.text_proj = nn.Linear(text_embed_dim, embed_dim)
|
||||
|
||||
if use_positional_embeddings or use_learned_positional_embeddings:
|
||||
persistent = use_learned_positional_embeddings
|
||||
pos_embedding = self._get_positional_embeddings(sample_height, sample_width, sample_frames)
|
||||
self.register_buffer("pos_embedding", pos_embedding, persistent=persistent)
|
||||
|
||||
def _get_positional_embeddings(self, sample_height: int, sample_width: int, sample_frames: int) -> torch.Tensor:
|
||||
post_patch_height = sample_height // self.patch_size
|
||||
post_patch_width = sample_width // self.patch_size
|
||||
post_time_compression_frames = (sample_frames - 1) // self.temporal_compression_ratio + 1
|
||||
num_patches = post_patch_height * post_patch_width * post_time_compression_frames
|
||||
|
||||
pos_embedding = get_3d_sincos_pos_embed(
|
||||
self.embed_dim,
|
||||
(post_patch_width, post_patch_height),
|
||||
post_time_compression_frames,
|
||||
self.spatial_interpolation_scale,
|
||||
self.temporal_interpolation_scale,
|
||||
)
|
||||
pos_embedding = torch.from_numpy(pos_embedding).flatten(0, 1)
|
||||
joint_pos_embedding = torch.zeros(
|
||||
1, self.max_text_seq_length + num_patches, self.embed_dim, requires_grad=False
|
||||
)
|
||||
joint_pos_embedding.data[:, self.max_text_seq_length :].copy_(pos_embedding)
|
||||
|
||||
return joint_pos_embedding
|
||||
|
||||
def forward(self, text_embeds: torch.Tensor, image_embeds: torch.Tensor):
|
||||
r"""
|
||||
Args:
|
||||
text_embeds (`torch.Tensor`):
|
||||
Input text embeddings. Expected shape: (batch_size, seq_length, embedding_dim).
|
||||
image_embeds (`torch.Tensor`):
|
||||
Input image embeddings. Expected shape: (batch_size, num_frames, channels, height, width).
|
||||
"""
|
||||
text_embeds = self.text_proj(text_embeds)
|
||||
|
||||
text_batch_size, text_seq_length, text_channels = text_embeds.shape
|
||||
batch_size, num_frames, channels, height, width = image_embeds.shape
|
||||
|
||||
if self.patch_size_t is None:
|
||||
image_embeds = image_embeds.reshape(-1, channels, height, width)
|
||||
image_embeds = self.proj(image_embeds)
|
||||
image_embeds = image_embeds.view(batch_size, num_frames, *image_embeds.shape[1:])
|
||||
image_embeds = image_embeds.flatten(3).transpose(2, 3) # [batch, num_frames, height x width, channels]
|
||||
image_embeds = image_embeds.flatten(1, 2) # [batch, num_frames x height x width, channels]
|
||||
else:
|
||||
p = self.patch_size
|
||||
p_t = self.patch_size_t
|
||||
|
||||
image_embeds = image_embeds.permute(0, 1, 3, 4, 2)
|
||||
# b, f, h, w, c => b, f // 2, 2, h // 2, 2, w // 2, 2, c
|
||||
image_embeds = image_embeds.reshape(
|
||||
batch_size, num_frames // p_t, p_t, height // p, p, width // p, p, channels
|
||||
)
|
||||
# b, f // 2, 2, h // 2, 2, w // 2, 2, c => b, f // 2, h // 2, w // 2, c, 2, 2, 2
|
||||
image_embeds = image_embeds.permute(0, 1, 3, 5, 7, 2, 4, 6).flatten(4, 7).flatten(1, 3)
|
||||
image_embeds = self.proj(image_embeds)
|
||||
|
||||
embeds = torch.cat(
|
||||
[text_embeds, image_embeds], dim=1
|
||||
).contiguous() # [batch, seq_length + num_frames x height x width, channels]
|
||||
|
||||
if self.use_positional_embeddings or self.use_learned_positional_embeddings:
|
||||
seq_length = height * width * num_frames // (self.patch_size**2)
|
||||
# pos_embeds = self.pos_embedding[:, : text_seq_length + seq_length]
|
||||
pos_embeds = self.pos_embedding
|
||||
emb_size = embeds.size()[-1]
|
||||
pos_embeds_without_text = pos_embeds[:, text_seq_length: ].view(1, self.post_time_compression_frames, self.post_patch_height, self.post_patch_width, emb_size)
|
||||
pos_embeds_without_text = pos_embeds_without_text.permute([0, 4, 1, 2, 3])
|
||||
pos_embeds_without_text = F.interpolate(pos_embeds_without_text,size=[self.post_time_compression_frames, height // self.patch_size, width // self.patch_size], mode='trilinear', align_corners=False)
|
||||
pos_embeds_without_text = pos_embeds_without_text.permute([0, 2, 3, 4, 1]).view(1, -1, emb_size)
|
||||
pos_embeds = torch.cat([pos_embeds[:, :text_seq_length], pos_embeds_without_text], dim = 1)
|
||||
pos_embeds = pos_embeds[:, : text_seq_length + seq_length]
|
||||
embeds = embeds + pos_embeds
|
||||
|
||||
return embeds
|
||||
|
||||
@maybe_allow_in_graph
|
||||
class CogVideoXBlock(nn.Module):
|
||||
@@ -294,6 +89,8 @@ class CogVideoXBlock(nn.Module):
|
||||
ff_inner_dim: Optional[int] = None,
|
||||
ff_bias: bool = True,
|
||||
attention_out_bias: bool = True,
|
||||
swa: bool = False,
|
||||
window_size: int = 1024,
|
||||
):
|
||||
super().__init__()
|
||||
|
||||
@@ -308,7 +105,7 @@ class CogVideoXBlock(nn.Module):
|
||||
eps=1e-6,
|
||||
bias=attention_bias,
|
||||
out_bias=attention_out_bias,
|
||||
processor=CogVideoXAttnProcessor2_0(),
|
||||
processor=CogVideoXSWAAttnProcessor2_0(window_size) if swa else CogVideoXAttnProcessor2_0(),
|
||||
)
|
||||
|
||||
# 2. Feed Forward
|
||||
@@ -329,6 +126,9 @@ class CogVideoXBlock(nn.Module):
|
||||
encoder_hidden_states: torch.Tensor,
|
||||
temb: torch.Tensor,
|
||||
image_rotary_emb: Optional[Tuple[torch.Tensor, torch.Tensor]] = None,
|
||||
num_frames: int = None,
|
||||
height: int = None,
|
||||
width: int = None,
|
||||
) -> torch.Tensor:
|
||||
text_seq_length = encoder_hidden_states.size(1)
|
||||
|
||||
@@ -342,6 +142,9 @@ class CogVideoXBlock(nn.Module):
|
||||
hidden_states=norm_hidden_states,
|
||||
encoder_hidden_states=norm_encoder_hidden_states,
|
||||
image_rotary_emb=image_rotary_emb,
|
||||
num_frames = num_frames,
|
||||
height = height,
|
||||
width = width,
|
||||
)
|
||||
|
||||
hidden_states = hidden_states + gate_msa * attn_hidden_states
|
||||
@@ -436,7 +239,6 @@ class CogVideoXTransformer3DModel(ModelMixin, ConfigMixin):
|
||||
sample_height: int = 60,
|
||||
sample_frames: int = 49,
|
||||
patch_size: int = 2,
|
||||
patch_size_t: Optional[int] = None,
|
||||
temporal_compression_ratio: int = 4,
|
||||
max_text_seq_length: int = 226,
|
||||
activation_fn: str = "gelu-approximate",
|
||||
@@ -446,45 +248,43 @@ class CogVideoXTransformer3DModel(ModelMixin, ConfigMixin):
|
||||
spatial_interpolation_scale: float = 1.875,
|
||||
temporal_interpolation_scale: float = 1.0,
|
||||
use_rotary_positional_embeddings: bool = False,
|
||||
use_learned_positional_embeddings: bool = False,
|
||||
patch_bias: bool = True,
|
||||
add_noise_in_inpaint_model: bool = False,
|
||||
swa: bool = False,
|
||||
window_size: int = 1024,
|
||||
):
|
||||
super().__init__()
|
||||
inner_dim = num_attention_heads * attention_head_dim
|
||||
self.patch_size_t = patch_size_t
|
||||
if not use_rotary_positional_embeddings and use_learned_positional_embeddings:
|
||||
raise ValueError(
|
||||
"There are no CogVideoX checkpoints available with disable rotary embeddings and learned positional "
|
||||
"embeddings. If you're using a custom model and/or believe this should be supported, please open an "
|
||||
"issue at https://github.com/huggingface/diffusers/issues."
|
||||
)
|
||||
|
||||
post_patch_height = sample_height // patch_size
|
||||
post_patch_width = sample_width // patch_size
|
||||
post_time_compression_frames = (sample_frames - 1) // temporal_compression_ratio + 1
|
||||
self.num_patches = post_patch_height * post_patch_width * post_time_compression_frames
|
||||
self.post_patch_height = post_patch_height
|
||||
self.post_patch_width = post_patch_width
|
||||
self.post_time_compression_frames = post_time_compression_frames
|
||||
self.patch_size = patch_size
|
||||
|
||||
# 1. Patch embedding
|
||||
self.patch_embed = CogVideoXPatchEmbed(
|
||||
patch_size=patch_size,
|
||||
patch_size_t=patch_size_t,
|
||||
in_channels=in_channels,
|
||||
embed_dim=inner_dim,
|
||||
text_embed_dim=text_embed_dim,
|
||||
bias=patch_bias,
|
||||
sample_width=sample_width,
|
||||
sample_height=sample_height,
|
||||
sample_frames=sample_frames,
|
||||
temporal_compression_ratio=temporal_compression_ratio,
|
||||
max_text_seq_length=max_text_seq_length,
|
||||
spatial_interpolation_scale=spatial_interpolation_scale,
|
||||
temporal_interpolation_scale=temporal_interpolation_scale,
|
||||
use_positional_embeddings=not use_rotary_positional_embeddings,
|
||||
use_learned_positional_embeddings=use_learned_positional_embeddings,
|
||||
)
|
||||
self.patch_embed = CogVideoXPatchEmbed(patch_size, in_channels, inner_dim, text_embed_dim, bias=True)
|
||||
self.embedding_dropout = nn.Dropout(dropout)
|
||||
|
||||
# 2. Time embeddings
|
||||
# 2. 3D positional embeddings
|
||||
spatial_pos_embedding = get_3d_sincos_pos_embed(
|
||||
inner_dim,
|
||||
(post_patch_width, post_patch_height),
|
||||
post_time_compression_frames,
|
||||
spatial_interpolation_scale,
|
||||
temporal_interpolation_scale,
|
||||
)
|
||||
spatial_pos_embedding = torch.from_numpy(spatial_pos_embedding).flatten(0, 1)
|
||||
pos_embedding = torch.zeros(1, max_text_seq_length + self.num_patches, inner_dim, requires_grad=False)
|
||||
pos_embedding.data[:, max_text_seq_length:].copy_(spatial_pos_embedding)
|
||||
self.register_buffer("pos_embedding", pos_embedding, persistent=False)
|
||||
|
||||
# 3. Time embeddings
|
||||
self.time_proj = Timesteps(inner_dim, flip_sin_to_cos, freq_shift)
|
||||
self.time_embedding = TimestepEmbedding(inner_dim, time_embed_dim, timestep_activation_fn)
|
||||
|
||||
# 3. Define spatio-temporal transformers blocks
|
||||
# 4. Define spatio-temporal transformers blocks
|
||||
self.transformer_blocks = nn.ModuleList(
|
||||
[
|
||||
CogVideoXBlock(
|
||||
@@ -497,13 +297,15 @@ class CogVideoXTransformer3DModel(ModelMixin, ConfigMixin):
|
||||
attention_bias=attention_bias,
|
||||
norm_elementwise_affine=norm_elementwise_affine,
|
||||
norm_eps=norm_eps,
|
||||
swa=swa,
|
||||
window_size=window_size,
|
||||
)
|
||||
for _ in range(num_layers)
|
||||
]
|
||||
)
|
||||
self.norm_final = nn.LayerNorm(inner_dim, norm_eps, norm_elementwise_affine)
|
||||
|
||||
# 4. Output blocks
|
||||
# 5. Output blocks
|
||||
self.norm_out = AdaLayerNorm(
|
||||
embedding_dim=time_embed_dim,
|
||||
output_dim=2 * inner_dim,
|
||||
@@ -511,32 +313,12 @@ class CogVideoXTransformer3DModel(ModelMixin, ConfigMixin):
|
||||
norm_eps=norm_eps,
|
||||
chunk_dim=1,
|
||||
)
|
||||
|
||||
if patch_size_t is None:
|
||||
# For CogVideox 1.0
|
||||
output_dim = patch_size * patch_size * out_channels
|
||||
else:
|
||||
# For CogVideoX 1.5
|
||||
output_dim = patch_size * patch_size * patch_size_t * out_channels
|
||||
|
||||
self.proj_out = nn.Linear(inner_dim, output_dim)
|
||||
self.proj_out = nn.Linear(inner_dim, patch_size * patch_size * out_channels)
|
||||
|
||||
self.gradient_checkpointing = False
|
||||
self.sp_world_size = 1
|
||||
self.sp_world_rank = 0
|
||||
|
||||
def _set_gradient_checkpointing(self, *args, **kwargs):
|
||||
if "value" in kwargs:
|
||||
self.gradient_checkpointing = kwargs["value"]
|
||||
elif "enable" in kwargs:
|
||||
self.gradient_checkpointing = kwargs["enable"]
|
||||
else:
|
||||
raise ValueError("Invalid set gradient checkpointing")
|
||||
|
||||
def enable_multi_gpus_inference(self,):
|
||||
self.sp_world_size = get_sequence_parallel_world_size()
|
||||
self.sp_world_rank = get_sequence_parallel_rank()
|
||||
self.set_attn_processor(CogVideoXMultiGPUsAttnProcessor2_0())
|
||||
def _set_gradient_checkpointing(self, module, value=False):
|
||||
self.gradient_checkpointing = value
|
||||
|
||||
@property
|
||||
# Copied from diffusers.models.unets.unet_2d_condition.UNet2DConditionModel.attn_processors
|
||||
@@ -645,20 +427,11 @@ class CogVideoXTransformer3DModel(ModelMixin, ConfigMixin):
|
||||
timestep: Union[int, float, torch.LongTensor],
|
||||
timestep_cond: Optional[torch.Tensor] = None,
|
||||
inpaint_latents: Optional[torch.Tensor] = None,
|
||||
control_latents: Optional[torch.Tensor] = None,
|
||||
image_rotary_emb: Optional[Tuple[torch.Tensor, torch.Tensor]] = None,
|
||||
return_dict: bool = True,
|
||||
):
|
||||
batch_size, num_frames, channels, height, width = hidden_states.shape
|
||||
if num_frames == 1 and self.patch_size_t is not None:
|
||||
hidden_states = torch.cat([hidden_states, torch.zeros_like(hidden_states)], dim=1)
|
||||
if inpaint_latents is not None:
|
||||
inpaint_latents = torch.concat([inpaint_latents, torch.zeros_like(inpaint_latents)], dim=1)
|
||||
if control_latents is not None:
|
||||
control_latents = torch.concat([control_latents, torch.zeros_like(control_latents)], dim=1)
|
||||
local_num_frames = num_frames + 1
|
||||
else:
|
||||
local_num_frames = num_frames
|
||||
p = self.config.patch_size
|
||||
|
||||
# 1. Time embedding
|
||||
timesteps = timestep
|
||||
@@ -673,27 +446,30 @@ class CogVideoXTransformer3DModel(ModelMixin, ConfigMixin):
|
||||
# 2. Patch embedding
|
||||
if inpaint_latents is not None:
|
||||
hidden_states = torch.concat([hidden_states, inpaint_latents], 2)
|
||||
if control_latents is not None:
|
||||
hidden_states = torch.concat([hidden_states, control_latents], 2)
|
||||
hidden_states = self.patch_embed(encoder_hidden_states, hidden_states)
|
||||
hidden_states = self.embedding_dropout(hidden_states)
|
||||
|
||||
# 3. Position embedding
|
||||
text_seq_length = encoder_hidden_states.shape[1]
|
||||
if not self.config.use_rotary_positional_embeddings:
|
||||
seq_length = height * width * num_frames // (self.config.patch_size**2)
|
||||
# pos_embeds = self.pos_embedding[:, : text_seq_length + seq_length]
|
||||
pos_embeds = self.pos_embedding
|
||||
emb_size = hidden_states.size()[-1]
|
||||
pos_embeds_without_text = pos_embeds[:, text_seq_length: ].view(1, self.post_time_compression_frames, self.post_patch_height, self.post_patch_width, emb_size)
|
||||
pos_embeds_without_text = pos_embeds_without_text.permute([0, 4, 1, 2, 3])
|
||||
pos_embeds_without_text = F.interpolate(pos_embeds_without_text,size=[self.post_time_compression_frames, height // self.config.patch_size, width // self.config.patch_size],mode='trilinear',align_corners=False)
|
||||
pos_embeds_without_text = pos_embeds_without_text.permute([0, 2, 3, 4, 1]).view(1, -1, emb_size)
|
||||
pos_embeds = torch.cat([pos_embeds[:, :text_seq_length], pos_embeds_without_text], dim = 1)
|
||||
pos_embeds = pos_embeds[:, : text_seq_length + seq_length]
|
||||
hidden_states = hidden_states + pos_embeds
|
||||
hidden_states = self.embedding_dropout(hidden_states)
|
||||
|
||||
encoder_hidden_states = hidden_states[:, :text_seq_length]
|
||||
hidden_states = hidden_states[:, text_seq_length:]
|
||||
|
||||
# Context Parallel
|
||||
if self.sp_world_size > 1:
|
||||
hidden_states = torch.chunk(hidden_states, self.sp_world_size, dim=1)[self.sp_world_rank]
|
||||
if image_rotary_emb is not None:
|
||||
image_rotary_emb = (
|
||||
torch.chunk(image_rotary_emb[0], self.sp_world_size, dim=0)[self.sp_world_rank],
|
||||
torch.chunk(image_rotary_emb[1], self.sp_world_size, dim=0)[self.sp_world_rank]
|
||||
)
|
||||
|
||||
# 3. Transformer blocks
|
||||
# 4. Transformer blocks
|
||||
for i, block in enumerate(self.transformer_blocks):
|
||||
if torch.is_grad_enabled() and self.gradient_checkpointing:
|
||||
if self.training and self.gradient_checkpointing:
|
||||
|
||||
def create_custom_forward(module):
|
||||
def custom_forward(*inputs):
|
||||
@@ -708,6 +484,9 @@ class CogVideoXTransformer3DModel(ModelMixin, ConfigMixin):
|
||||
encoder_hidden_states,
|
||||
emb,
|
||||
image_rotary_emb,
|
||||
num_frames,
|
||||
height // p,
|
||||
width // p,
|
||||
**ckpt_kwargs,
|
||||
)
|
||||
else:
|
||||
@@ -716,6 +495,9 @@ class CogVideoXTransformer3DModel(ModelMixin, ConfigMixin):
|
||||
encoder_hidden_states=encoder_hidden_states,
|
||||
temb=emb,
|
||||
image_rotary_emb=image_rotary_emb,
|
||||
num_frames=num_frames,
|
||||
height=height // p,
|
||||
width=width // p,
|
||||
)
|
||||
|
||||
if not self.config.use_rotary_positional_embeddings:
|
||||
@@ -727,38 +509,20 @@ class CogVideoXTransformer3DModel(ModelMixin, ConfigMixin):
|
||||
hidden_states = self.norm_final(hidden_states)
|
||||
hidden_states = hidden_states[:, text_seq_length:]
|
||||
|
||||
# 4. Final block
|
||||
# 5. Final block
|
||||
hidden_states = self.norm_out(hidden_states, temb=emb)
|
||||
hidden_states = self.proj_out(hidden_states)
|
||||
|
||||
if self.sp_world_size > 1:
|
||||
hidden_states = get_sp_group().all_gather(hidden_states, dim=1)
|
||||
|
||||
# 5. Unpatchify
|
||||
p = self.config.patch_size
|
||||
p_t = self.config.patch_size_t
|
||||
|
||||
if p_t is None:
|
||||
output = hidden_states.reshape(batch_size, local_num_frames, height // p, width // p, -1, p, p)
|
||||
output = output.permute(0, 1, 4, 2, 5, 3, 6).flatten(5, 6).flatten(3, 4)
|
||||
else:
|
||||
output = hidden_states.reshape(
|
||||
batch_size, (local_num_frames + p_t - 1) // p_t, height // p, width // p, -1, p_t, p, p
|
||||
)
|
||||
output = output.permute(0, 1, 5, 4, 2, 6, 3, 7).flatten(6, 7).flatten(4, 5).flatten(1, 2)
|
||||
|
||||
if num_frames == 1:
|
||||
output = output[:, :num_frames, :]
|
||||
# 6. Unpatchify
|
||||
output = hidden_states.reshape(batch_size, num_frames, height // p, width // p, channels, p, p)
|
||||
output = output.permute(0, 1, 4, 2, 5, 3, 6).flatten(5, 6).flatten(3, 4)
|
||||
|
||||
if not return_dict:
|
||||
return (output,)
|
||||
return Transformer2DModelOutput(sample=output)
|
||||
|
||||
@classmethod
|
||||
def from_pretrained(
|
||||
cls, pretrained_model_path, subfolder=None, transformer_additional_kwargs={},
|
||||
low_cpu_mem_usage=False, torch_dtype=torch.bfloat16
|
||||
):
|
||||
def from_pretrained_2d(cls, pretrained_model_path, subfolder=None, transformer_additional_kwargs={}):
|
||||
if subfolder is not None:
|
||||
pretrained_model_path = os.path.join(pretrained_model_path, subfolder)
|
||||
print(f"loaded 3D transformer's pretrained weights from {pretrained_model_path} ...")
|
||||
@@ -770,119 +534,22 @@ class CogVideoXTransformer3DModel(ModelMixin, ConfigMixin):
|
||||
config = json.load(f)
|
||||
|
||||
from diffusers.utils import WEIGHTS_NAME
|
||||
model = cls.from_config(config, **transformer_additional_kwargs)
|
||||
model_file = os.path.join(pretrained_model_path, WEIGHTS_NAME)
|
||||
model_file_safetensors = model_file.replace(".bin", ".safetensors")
|
||||
|
||||
if "dict_mapping" in transformer_additional_kwargs.keys():
|
||||
for key in transformer_additional_kwargs["dict_mapping"]:
|
||||
transformer_additional_kwargs[transformer_additional_kwargs["dict_mapping"][key]] = config[key]
|
||||
|
||||
if low_cpu_mem_usage:
|
||||
try:
|
||||
import re
|
||||
|
||||
from diffusers import __version__ as diffusers_version
|
||||
if diffusers_version >= "0.33.0":
|
||||
from diffusers.models.model_loading_utils import \
|
||||
load_model_dict_into_meta
|
||||
else:
|
||||
from diffusers.models.modeling_utils import \
|
||||
load_model_dict_into_meta
|
||||
from diffusers.utils import is_accelerate_available
|
||||
if is_accelerate_available():
|
||||
import accelerate
|
||||
|
||||
# Instantiate model with empty weights
|
||||
with accelerate.init_empty_weights():
|
||||
model = cls.from_config(config, **transformer_additional_kwargs)
|
||||
|
||||
param_device = "cpu"
|
||||
if os.path.exists(model_file):
|
||||
state_dict = torch.load(model_file, map_location="cpu")
|
||||
elif os.path.exists(model_file_safetensors):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(model_file_safetensors)
|
||||
else:
|
||||
from safetensors.torch import load_file, safe_open
|
||||
model_files_safetensors = glob.glob(os.path.join(pretrained_model_path, "*.safetensors"))
|
||||
state_dict = {}
|
||||
for _model_file_safetensors in model_files_safetensors:
|
||||
_state_dict = load_file(_model_file_safetensors)
|
||||
for key in _state_dict:
|
||||
state_dict[key] = _state_dict[key]
|
||||
model._convert_deprecated_attention_blocks(state_dict)
|
||||
|
||||
if diffusers_version >= "0.33.0":
|
||||
# Diffusers has refactored `load_model_dict_into_meta` since version 0.33.0 in this commit:
|
||||
# https://github.com/huggingface/diffusers/commit/f5929e03060d56063ff34b25a8308833bec7c785.
|
||||
load_model_dict_into_meta(
|
||||
model,
|
||||
state_dict,
|
||||
dtype=torch_dtype,
|
||||
model_name_or_path=pretrained_model_path,
|
||||
)
|
||||
else:
|
||||
# move the params from meta device to cpu
|
||||
missing_keys = set(model.state_dict().keys()) - set(state_dict.keys())
|
||||
if len(missing_keys) > 0:
|
||||
raise ValueError(
|
||||
f"Cannot load {cls} from {pretrained_model_path} because the following keys are"
|
||||
f" missing: \n {', '.join(missing_keys)}. \n Please make sure to pass"
|
||||
" `low_cpu_mem_usage=False` and `device_map=None` if you want to randomly initialize"
|
||||
" those weights or else make sure your checkpoint file is correct."
|
||||
)
|
||||
|
||||
unexpected_keys = load_model_dict_into_meta(
|
||||
model,
|
||||
state_dict,
|
||||
device=param_device,
|
||||
dtype=torch_dtype,
|
||||
model_name_or_path=pretrained_model_path,
|
||||
)
|
||||
|
||||
if cls._keys_to_ignore_on_load_unexpected is not None:
|
||||
for pat in cls._keys_to_ignore_on_load_unexpected:
|
||||
unexpected_keys = [k for k in unexpected_keys if re.search(pat, k) is None]
|
||||
|
||||
if len(unexpected_keys) > 0:
|
||||
print(
|
||||
f"Some weights of the model checkpoint were not used when initializing {cls.__name__}: \n {[', '.join(unexpected_keys)]}"
|
||||
)
|
||||
|
||||
return model
|
||||
except Exception as e:
|
||||
print(
|
||||
f"The low_cpu_mem_usage mode is not work because {e}. Use low_cpu_mem_usage=False instead."
|
||||
)
|
||||
|
||||
model = cls.from_config(config, **transformer_additional_kwargs)
|
||||
if os.path.exists(model_file):
|
||||
state_dict = torch.load(model_file, map_location="cpu")
|
||||
elif os.path.exists(model_file_safetensors):
|
||||
if os.path.exists(model_file_safetensors):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(model_file_safetensors)
|
||||
else:
|
||||
from safetensors.torch import load_file, safe_open
|
||||
model_files_safetensors = glob.glob(os.path.join(pretrained_model_path, "*.safetensors"))
|
||||
state_dict = {}
|
||||
for _model_file_safetensors in model_files_safetensors:
|
||||
_state_dict = load_file(_model_file_safetensors)
|
||||
for key in _state_dict:
|
||||
state_dict[key] = _state_dict[key]
|
||||
if not os.path.isfile(model_file):
|
||||
raise RuntimeError(f"{model_file} does not exist")
|
||||
state_dict = torch.load(model_file, map_location="cpu")
|
||||
|
||||
if model.state_dict()['patch_embed.proj.weight'].size() != state_dict['patch_embed.proj.weight'].size():
|
||||
new_shape = model.state_dict()['patch_embed.proj.weight'].size()
|
||||
if len(new_shape) == 5:
|
||||
state_dict['patch_embed.proj.weight'] = state_dict['patch_embed.proj.weight'].unsqueeze(2).expand(new_shape).clone()
|
||||
state_dict['patch_embed.proj.weight'][:, :, :-1] = 0
|
||||
elif len(new_shape) == 2:
|
||||
if model.state_dict()['patch_embed.proj.weight'].size()[1] > state_dict['patch_embed.proj.weight'].size()[1]:
|
||||
model.state_dict()['patch_embed.proj.weight'][:, :state_dict['patch_embed.proj.weight'].size()[1]] = state_dict['patch_embed.proj.weight']
|
||||
model.state_dict()['patch_embed.proj.weight'][:, state_dict['patch_embed.proj.weight'].size()[1]:] = 0
|
||||
state_dict['patch_embed.proj.weight'] = model.state_dict()['patch_embed.proj.weight']
|
||||
else:
|
||||
model.state_dict()['patch_embed.proj.weight'][:, :] = state_dict['patch_embed.proj.weight'][:, :model.state_dict()['patch_embed.proj.weight'].size()[1]]
|
||||
state_dict['patch_embed.proj.weight'] = model.state_dict()['patch_embed.proj.weight']
|
||||
else:
|
||||
if model.state_dict()['patch_embed.proj.weight'].size()[1] > state_dict['patch_embed.proj.weight'].size()[1]:
|
||||
model.state_dict()['patch_embed.proj.weight'][:, :state_dict['patch_embed.proj.weight'].size()[1], :, :] = state_dict['patch_embed.proj.weight']
|
||||
@@ -898,18 +565,16 @@ class CogVideoXTransformer3DModel(ModelMixin, ConfigMixin):
|
||||
tmp_state_dict[key] = state_dict[key]
|
||||
else:
|
||||
print(key, "Size don't match, skip")
|
||||
|
||||
state_dict = tmp_state_dict
|
||||
|
||||
m, u = model.load_state_dict(state_dict, strict=False)
|
||||
print(f"### missing keys: {len(m)}; \n### unexpected keys: {len(u)};")
|
||||
print(m)
|
||||
|
||||
params = [p.numel() if "." in n else 0 for n, p in model.named_parameters()]
|
||||
print(f"### All Parameters: {sum(params) / 1e6} M")
|
||||
params = [p.numel() if "mamba" in n else 0 for n, p in model.named_parameters()]
|
||||
print(f"### Mamba Parameters: {sum(params) / 1e6} M")
|
||||
|
||||
params = [p.numel() if "attn1." in n else 0 for n, p in model.named_parameters()]
|
||||
print(f"### attn1 Parameters: {sum(params) / 1e6} M")
|
||||
|
||||
model = model.to(torch_dtype)
|
||||
return model
|
||||
@@ -16,21 +16,20 @@
|
||||
import inspect
|
||||
import math
|
||||
from dataclasses import dataclass
|
||||
from typing import Any, Callable, Dict, List, Optional, Tuple, Union
|
||||
from typing import Callable, Dict, List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from transformers import T5EncoderModel, T5Tokenizer
|
||||
|
||||
from diffusers.callbacks import MultiPipelineCallbacks, PipelineCallback
|
||||
from diffusers.models.embeddings import get_1d_rotary_pos_embed
|
||||
from diffusers.models import AutoencoderKLCogVideoX, CogVideoXTransformer3DModel
|
||||
from diffusers.models.embeddings import get_3d_rotary_pos_embed
|
||||
from diffusers.pipelines.pipeline_utils import DiffusionPipeline
|
||||
from diffusers.schedulers import CogVideoXDDIMScheduler, CogVideoXDPMScheduler
|
||||
from diffusers.utils import BaseOutput, logging, replace_example_docstring
|
||||
from diffusers.utils.torch_utils import randn_tensor
|
||||
from diffusers.video_processor import VideoProcessor
|
||||
|
||||
from ..models import (AutoencoderKLCogVideoX,
|
||||
CogVideoXTransformer3DModel, T5EncoderModel,
|
||||
T5Tokenizer)
|
||||
|
||||
logger = logging.get_logger(__name__) # pylint: disable=invalid-name
|
||||
|
||||
@@ -38,106 +37,26 @@ logger = logging.get_logger(__name__) # pylint: disable=invalid-name
|
||||
EXAMPLE_DOC_STRING = """
|
||||
Examples:
|
||||
```python
|
||||
pass
|
||||
>>> import torch
|
||||
>>> from diffusers import CogVideoX_Fun_Pipeline
|
||||
>>> from diffusers.utils import export_to_video
|
||||
|
||||
>>> # Models: "THUDM/CogVideoX-2b" or "THUDM/CogVideoX-5b"
|
||||
>>> pipe = CogVideoX_Fun_Pipeline.from_pretrained("THUDM/CogVideoX-2b", torch_dtype=torch.float16).to("cuda")
|
||||
>>> prompt = (
|
||||
... "A panda, dressed in a small, red jacket and a tiny hat, sits on a wooden stool in a serene bamboo forest. "
|
||||
... "The panda's fluffy paws strum a miniature acoustic guitar, producing soft, melodic tunes. Nearby, a few other "
|
||||
... "pandas gather, watching curiously and some clapping in rhythm. Sunlight filters through the tall bamboo, "
|
||||
... "casting a gentle glow on the scene. The panda's face is expressive, showing concentration and joy as it plays. "
|
||||
... "The background includes a small, flowing stream and vibrant green foliage, enhancing the peaceful and magical "
|
||||
... "atmosphere of this unique musical performance."
|
||||
... )
|
||||
>>> video = pipe(prompt=prompt, guidance_scale=6, num_inference_steps=50).frames[0]
|
||||
>>> export_to_video(video, "output.mp4", fps=8)
|
||||
```
|
||||
"""
|
||||
|
||||
|
||||
# Copied from diffusers.models.embeddings.get_3d_rotary_pos_embed
|
||||
def get_3d_rotary_pos_embed(
|
||||
embed_dim,
|
||||
crops_coords,
|
||||
grid_size,
|
||||
temporal_size,
|
||||
theta: int = 10000,
|
||||
use_real: bool = True,
|
||||
grid_type: str = "linspace",
|
||||
max_size: Optional[Tuple[int, int]] = None,
|
||||
) -> Union[torch.Tensor, Tuple[torch.Tensor, torch.Tensor]]:
|
||||
"""
|
||||
RoPE for video tokens with 3D structure.
|
||||
|
||||
Args:
|
||||
embed_dim: (`int`):
|
||||
The embedding dimension size, corresponding to hidden_size_head.
|
||||
crops_coords (`Tuple[int]`):
|
||||
The top-left and bottom-right coordinates of the crop.
|
||||
grid_size (`Tuple[int]`):
|
||||
The grid size of the spatial positional embedding (height, width).
|
||||
temporal_size (`int`):
|
||||
The size of the temporal dimension.
|
||||
theta (`float`):
|
||||
Scaling factor for frequency computation.
|
||||
grid_type (`str`):
|
||||
Whether to use "linspace" or "slice" to compute grids.
|
||||
|
||||
Returns:
|
||||
`torch.Tensor`: positional embedding with shape `(temporal_size * grid_size[0] * grid_size[1], embed_dim/2)`.
|
||||
"""
|
||||
if use_real is not True:
|
||||
raise ValueError(" `use_real = False` is not currently supported for get_3d_rotary_pos_embed")
|
||||
|
||||
if grid_type == "linspace":
|
||||
start, stop = crops_coords
|
||||
grid_size_h, grid_size_w = grid_size
|
||||
grid_h = np.linspace(start[0], stop[0], grid_size_h, endpoint=False, dtype=np.float32)
|
||||
grid_w = np.linspace(start[1], stop[1], grid_size_w, endpoint=False, dtype=np.float32)
|
||||
grid_t = np.arange(temporal_size, dtype=np.float32)
|
||||
grid_t = np.linspace(0, temporal_size, temporal_size, endpoint=False, dtype=np.float32)
|
||||
elif grid_type == "slice":
|
||||
max_h, max_w = max_size
|
||||
grid_size_h, grid_size_w = grid_size
|
||||
grid_h = np.arange(max_h, dtype=np.float32)
|
||||
grid_w = np.arange(max_w, dtype=np.float32)
|
||||
grid_t = np.arange(temporal_size, dtype=np.float32)
|
||||
else:
|
||||
raise ValueError("Invalid value passed for `grid_type`.")
|
||||
|
||||
# Compute dimensions for each axis
|
||||
dim_t = embed_dim // 4
|
||||
dim_h = embed_dim // 8 * 3
|
||||
dim_w = embed_dim // 8 * 3
|
||||
|
||||
# Temporal frequencies
|
||||
freqs_t = get_1d_rotary_pos_embed(dim_t, grid_t, use_real=True)
|
||||
# Spatial frequencies for height and width
|
||||
freqs_h = get_1d_rotary_pos_embed(dim_h, grid_h, use_real=True)
|
||||
freqs_w = get_1d_rotary_pos_embed(dim_w, grid_w, use_real=True)
|
||||
|
||||
# BroadCast and concatenate temporal and spaial frequencie (height and width) into a 3d tensor
|
||||
def combine_time_height_width(freqs_t, freqs_h, freqs_w):
|
||||
freqs_t = freqs_t[:, None, None, :].expand(
|
||||
-1, grid_size_h, grid_size_w, -1
|
||||
) # temporal_size, grid_size_h, grid_size_w, dim_t
|
||||
freqs_h = freqs_h[None, :, None, :].expand(
|
||||
temporal_size, -1, grid_size_w, -1
|
||||
) # temporal_size, grid_size_h, grid_size_2, dim_h
|
||||
freqs_w = freqs_w[None, None, :, :].expand(
|
||||
temporal_size, grid_size_h, -1, -1
|
||||
) # temporal_size, grid_size_h, grid_size_2, dim_w
|
||||
|
||||
freqs = torch.cat(
|
||||
[freqs_t, freqs_h, freqs_w], dim=-1
|
||||
) # temporal_size, grid_size_h, grid_size_w, (dim_t + dim_h + dim_w)
|
||||
freqs = freqs.view(
|
||||
temporal_size * grid_size_h * grid_size_w, -1
|
||||
) # (temporal_size * grid_size_h * grid_size_w), (dim_t + dim_h + dim_w)
|
||||
return freqs
|
||||
|
||||
t_cos, t_sin = freqs_t # both t_cos and t_sin has shape: temporal_size, dim_t
|
||||
h_cos, h_sin = freqs_h # both h_cos and h_sin has shape: grid_size_h, dim_h
|
||||
w_cos, w_sin = freqs_w # both w_cos and w_sin has shape: grid_size_w, dim_w
|
||||
|
||||
if grid_type == "slice":
|
||||
t_cos, t_sin = t_cos[:temporal_size], t_sin[:temporal_size]
|
||||
h_cos, h_sin = h_cos[:grid_size_h], h_sin[:grid_size_h]
|
||||
w_cos, w_sin = w_cos[:grid_size_w], w_sin[:grid_size_w]
|
||||
|
||||
cos = combine_time_height_width(t_cos, h_cos, w_cos)
|
||||
sin = combine_time_height_width(t_sin, h_sin, w_sin)
|
||||
return cos, sin
|
||||
|
||||
|
||||
# Similar to diffusers.pipelines.hunyuandit.pipeline_hunyuandit.get_resize_crop_region_for_grid
|
||||
def get_resize_crop_region_for_grid(src, tgt_width, tgt_height):
|
||||
tw = tgt_width
|
||||
@@ -218,7 +137,7 @@ def retrieve_timesteps(
|
||||
|
||||
|
||||
@dataclass
|
||||
class CogVideoXFunPipelineOutput(BaseOutput):
|
||||
class CogVideoX_Fun_PipelineOutput(BaseOutput):
|
||||
r"""
|
||||
Output class for CogVideo pipelines.
|
||||
|
||||
@@ -232,7 +151,7 @@ class CogVideoXFunPipelineOutput(BaseOutput):
|
||||
videos: torch.Tensor
|
||||
|
||||
|
||||
class CogVideoXFunPipeline(DiffusionPipeline):
|
||||
class CogVideoX_Fun_Pipeline(DiffusionPipeline):
|
||||
r"""
|
||||
Pipeline for text-to-video generation using CogVideoX_Fun.
|
||||
|
||||
@@ -412,12 +331,6 @@ class CogVideoXFunPipeline(DiffusionPipeline):
|
||||
def prepare_latents(
|
||||
self, batch_size, num_channels_latents, num_frames, height, width, dtype, device, generator, latents=None
|
||||
):
|
||||
if isinstance(generator, list) and len(generator) != batch_size:
|
||||
raise ValueError(
|
||||
f"You have passed a list of generators of length {len(generator)}, but requested an effective batch"
|
||||
f" size of {batch_size}. Make sure the batch size matches the length of the generators."
|
||||
)
|
||||
|
||||
shape = (
|
||||
batch_size,
|
||||
(num_frames - 1) // self.vae_scale_factor_temporal + 1,
|
||||
@@ -425,6 +338,11 @@ class CogVideoXFunPipeline(DiffusionPipeline):
|
||||
height // self.vae_scale_factor_spatial,
|
||||
width // self.vae_scale_factor_spatial,
|
||||
)
|
||||
if isinstance(generator, list) and len(generator) != batch_size:
|
||||
raise ValueError(
|
||||
f"You have passed a list of generators of length {len(generator)}, but requested an effective batch"
|
||||
f" size of {batch_size}. Make sure the batch size matches the length of the generators."
|
||||
)
|
||||
|
||||
if latents is None:
|
||||
latents = randn_tensor(shape, generator=generator, device=device, dtype=dtype)
|
||||
@@ -537,36 +455,19 @@ class CogVideoXFunPipeline(DiffusionPipeline):
|
||||
) -> Tuple[torch.Tensor, torch.Tensor]:
|
||||
grid_height = height // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
|
||||
grid_width = width // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
|
||||
base_size_width = 720 // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
|
||||
base_size_height = 480 // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
|
||||
|
||||
p = self.transformer.config.patch_size
|
||||
p_t = self.transformer.config.patch_size_t
|
||||
|
||||
base_size_width = self.transformer.config.sample_width // p
|
||||
base_size_height = self.transformer.config.sample_height // p
|
||||
|
||||
if p_t is None:
|
||||
# CogVideoX 1.0
|
||||
grid_crops_coords = get_resize_crop_region_for_grid(
|
||||
(grid_height, grid_width), base_size_width, base_size_height
|
||||
)
|
||||
freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
|
||||
embed_dim=self.transformer.config.attention_head_dim,
|
||||
crops_coords=grid_crops_coords,
|
||||
grid_size=(grid_height, grid_width),
|
||||
temporal_size=num_frames,
|
||||
)
|
||||
else:
|
||||
# CogVideoX 1.5
|
||||
base_num_frames = (num_frames + p_t - 1) // p_t
|
||||
|
||||
freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
|
||||
embed_dim=self.transformer.config.attention_head_dim,
|
||||
crops_coords=None,
|
||||
grid_size=(grid_height, grid_width),
|
||||
temporal_size=base_num_frames,
|
||||
grid_type="slice",
|
||||
max_size=(base_size_height, base_size_width),
|
||||
)
|
||||
grid_crops_coords = get_resize_crop_region_for_grid(
|
||||
(grid_height, grid_width), base_size_width, base_size_height
|
||||
)
|
||||
freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
|
||||
embed_dim=self.transformer.config.attention_head_dim,
|
||||
crops_coords=grid_crops_coords,
|
||||
grid_size=(grid_height, grid_width),
|
||||
temporal_size=num_frames,
|
||||
use_real=True,
|
||||
)
|
||||
|
||||
freqs_cos = freqs_cos.to(device=device)
|
||||
freqs_sin = freqs_sin.to(device=device)
|
||||
@@ -580,10 +481,6 @@ class CogVideoXFunPipeline(DiffusionPipeline):
|
||||
def num_timesteps(self):
|
||||
return self._num_timesteps
|
||||
|
||||
@property
|
||||
def attention_kwargs(self):
|
||||
return self._attention_kwargs
|
||||
|
||||
@property
|
||||
def interrupt(self):
|
||||
return self._interrupt
|
||||
@@ -612,10 +509,9 @@ class CogVideoXFunPipeline(DiffusionPipeline):
|
||||
callback_on_step_end: Optional[
|
||||
Union[Callable[[int, int, Dict], None], PipelineCallback, MultiPipelineCallbacks]
|
||||
] = None,
|
||||
attention_kwargs: Optional[Dict[str, Any]] = None,
|
||||
callback_on_step_end_tensor_inputs: List[str] = ["latents"],
|
||||
max_sequence_length: int = 226,
|
||||
) -> Union[CogVideoXFunPipelineOutput, Tuple]:
|
||||
) -> Union[CogVideoX_Fun_PipelineOutput, Tuple]:
|
||||
"""
|
||||
Function invoked when calling the pipeline for generation.
|
||||
|
||||
@@ -687,18 +583,21 @@ class CogVideoXFunPipeline(DiffusionPipeline):
|
||||
Examples:
|
||||
|
||||
Returns:
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoXFunPipelineOutput`] or `tuple`:
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoXFunPipelineOutput`] if `return_dict` is True, otherwise a
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_Fun_PipelineOutput`] or `tuple`:
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_Fun_PipelineOutput`] if `return_dict` is True, otherwise a
|
||||
`tuple`. When returning a tuple, the first element is a list with the generated images.
|
||||
"""
|
||||
|
||||
if num_frames > 49:
|
||||
raise ValueError(
|
||||
"The number of frames must be less than 49 for now due to static positional embeddings. This will be updated in the future to remove this limitation."
|
||||
)
|
||||
|
||||
if isinstance(callback_on_step_end, (PipelineCallback, MultiPipelineCallbacks)):
|
||||
callback_on_step_end_tensor_inputs = callback_on_step_end.tensor_inputs
|
||||
|
||||
height = height or self.transformer.config.sample_height * self.vae_scale_factor_spatial
|
||||
width = width or self.transformer.config.sample_width * self.vae_scale_factor_spatial
|
||||
num_frames = num_frames or self.transformer.config.sample_frames
|
||||
|
||||
height = height or self.transformer.config.sample_size * self.vae_scale_factor_spatial
|
||||
width = width or self.transformer.config.sample_size * self.vae_scale_factor_spatial
|
||||
num_videos_per_prompt = 1
|
||||
|
||||
# 1. Check inputs. Raise error if not correct
|
||||
@@ -712,7 +611,6 @@ class CogVideoXFunPipeline(DiffusionPipeline):
|
||||
negative_prompt_embeds,
|
||||
)
|
||||
self._guidance_scale = guidance_scale
|
||||
self._attention_kwargs = attention_kwargs
|
||||
self._interrupt = False
|
||||
|
||||
# 2. Default call parameters
|
||||
@@ -748,16 +646,7 @@ class CogVideoXFunPipeline(DiffusionPipeline):
|
||||
timesteps, num_inference_steps = retrieve_timesteps(self.scheduler, num_inference_steps, device, timesteps)
|
||||
self._num_timesteps = len(timesteps)
|
||||
|
||||
# 5. Prepare latents
|
||||
latent_frames = (num_frames - 1) // self.vae_scale_factor_temporal + 1
|
||||
|
||||
# For CogVideoX 1.5, the latent frames should be padded to make it divisible by patch_size_t
|
||||
patch_size_t = self.transformer.config.patch_size_t
|
||||
additional_frames = 0
|
||||
if num_frames != 1 and patch_size_t is not None and latent_frames % patch_size_t != 0:
|
||||
additional_frames = patch_size_t - latent_frames % patch_size_t
|
||||
num_frames += additional_frames * self.vae_scale_factor_temporal
|
||||
|
||||
# 5. Prepare latents.
|
||||
latent_channels = self.transformer.config.in_channels
|
||||
latents = self.prepare_latents(
|
||||
batch_size * num_videos_per_prompt,
|
||||
@@ -859,4 +748,4 @@ class CogVideoXFunPipeline(DiffusionPipeline):
|
||||
if not return_dict:
|
||||
video = torch.from_numpy(video)
|
||||
|
||||
return CogVideoXFunPipelineOutput(videos=video)
|
||||
return CogVideoX_Fun_PipelineOutput(videos=video)
|
||||
@@ -16,24 +16,24 @@
|
||||
import inspect
|
||||
import math
|
||||
from dataclasses import dataclass
|
||||
from typing import Any, Callable, Dict, List, Optional, Tuple, Union
|
||||
from typing import Callable, Dict, List, Optional, Tuple, Union
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from einops import rearrange
|
||||
from transformers import T5EncoderModel, T5Tokenizer
|
||||
|
||||
from diffusers.callbacks import MultiPipelineCallbacks, PipelineCallback
|
||||
from diffusers.image_processor import VaeImageProcessor
|
||||
from diffusers.models.embeddings import get_1d_rotary_pos_embed
|
||||
from diffusers.models import AutoencoderKLCogVideoX, CogVideoXTransformer3DModel
|
||||
from diffusers.models.embeddings import get_3d_rotary_pos_embed
|
||||
from diffusers.pipelines.pipeline_utils import DiffusionPipeline
|
||||
from diffusers.schedulers import CogVideoXDDIMScheduler, CogVideoXDPMScheduler
|
||||
from diffusers.utils import BaseOutput, logging, replace_example_docstring
|
||||
from diffusers.utils.torch_utils import randn_tensor
|
||||
from diffusers.video_processor import VideoProcessor
|
||||
from diffusers.image_processor import VaeImageProcessor
|
||||
from einops import rearrange
|
||||
|
||||
from ..models import (AutoencoderKLCogVideoX,
|
||||
CogVideoXTransformer3DModel, T5EncoderModel,
|
||||
T5Tokenizer)
|
||||
|
||||
logger = logging.get_logger(__name__) # pylint: disable=invalid-name
|
||||
|
||||
@@ -41,104 +41,25 @@ logger = logging.get_logger(__name__) # pylint: disable=invalid-name
|
||||
EXAMPLE_DOC_STRING = """
|
||||
Examples:
|
||||
```python
|
||||
pass
|
||||
>>> import torch
|
||||
>>> from diffusers import CogVideoX_Fun_Pipeline
|
||||
>>> from diffusers.utils import export_to_video
|
||||
|
||||
>>> # Models: "THUDM/CogVideoX-2b" or "THUDM/CogVideoX-5b"
|
||||
>>> pipe = CogVideoX_Fun_Pipeline.from_pretrained("THUDM/CogVideoX-2b", torch_dtype=torch.float16).to("cuda")
|
||||
>>> prompt = (
|
||||
... "A panda, dressed in a small, red jacket and a tiny hat, sits on a wooden stool in a serene bamboo forest. "
|
||||
... "The panda's fluffy paws strum a miniature acoustic guitar, producing soft, melodic tunes. Nearby, a few other "
|
||||
... "pandas gather, watching curiously and some clapping in rhythm. Sunlight filters through the tall bamboo, "
|
||||
... "casting a gentle glow on the scene. The panda's face is expressive, showing concentration and joy as it plays. "
|
||||
... "The background includes a small, flowing stream and vibrant green foliage, enhancing the peaceful and magical "
|
||||
... "atmosphere of this unique musical performance."
|
||||
... )
|
||||
>>> video = pipe(prompt=prompt, guidance_scale=6, num_inference_steps=50).frames[0]
|
||||
>>> export_to_video(video, "output.mp4", fps=8)
|
||||
```
|
||||
"""
|
||||
|
||||
# Copied from diffusers.models.embeddings.get_3d_rotary_pos_embed
|
||||
def get_3d_rotary_pos_embed(
|
||||
embed_dim,
|
||||
crops_coords,
|
||||
grid_size,
|
||||
temporal_size,
|
||||
theta: int = 10000,
|
||||
use_real: bool = True,
|
||||
grid_type: str = "linspace",
|
||||
max_size: Optional[Tuple[int, int]] = None,
|
||||
) -> Union[torch.Tensor, Tuple[torch.Tensor, torch.Tensor]]:
|
||||
"""
|
||||
RoPE for video tokens with 3D structure.
|
||||
|
||||
Args:
|
||||
embed_dim: (`int`):
|
||||
The embedding dimension size, corresponding to hidden_size_head.
|
||||
crops_coords (`Tuple[int]`):
|
||||
The top-left and bottom-right coordinates of the crop.
|
||||
grid_size (`Tuple[int]`):
|
||||
The grid size of the spatial positional embedding (height, width).
|
||||
temporal_size (`int`):
|
||||
The size of the temporal dimension.
|
||||
theta (`float`):
|
||||
Scaling factor for frequency computation.
|
||||
grid_type (`str`):
|
||||
Whether to use "linspace" or "slice" to compute grids.
|
||||
|
||||
Returns:
|
||||
`torch.Tensor`: positional embedding with shape `(temporal_size * grid_size[0] * grid_size[1], embed_dim/2)`.
|
||||
"""
|
||||
if use_real is not True:
|
||||
raise ValueError(" `use_real = False` is not currently supported for get_3d_rotary_pos_embed")
|
||||
|
||||
if grid_type == "linspace":
|
||||
start, stop = crops_coords
|
||||
grid_size_h, grid_size_w = grid_size
|
||||
grid_h = np.linspace(start[0], stop[0], grid_size_h, endpoint=False, dtype=np.float32)
|
||||
grid_w = np.linspace(start[1], stop[1], grid_size_w, endpoint=False, dtype=np.float32)
|
||||
grid_t = np.arange(temporal_size, dtype=np.float32)
|
||||
grid_t = np.linspace(0, temporal_size, temporal_size, endpoint=False, dtype=np.float32)
|
||||
elif grid_type == "slice":
|
||||
max_h, max_w = max_size
|
||||
grid_size_h, grid_size_w = grid_size
|
||||
grid_h = np.arange(max_h, dtype=np.float32)
|
||||
grid_w = np.arange(max_w, dtype=np.float32)
|
||||
grid_t = np.arange(temporal_size, dtype=np.float32)
|
||||
else:
|
||||
raise ValueError("Invalid value passed for `grid_type`.")
|
||||
|
||||
# Compute dimensions for each axis
|
||||
dim_t = embed_dim // 4
|
||||
dim_h = embed_dim // 8 * 3
|
||||
dim_w = embed_dim // 8 * 3
|
||||
|
||||
# Temporal frequencies
|
||||
freqs_t = get_1d_rotary_pos_embed(dim_t, grid_t, use_real=True)
|
||||
# Spatial frequencies for height and width
|
||||
freqs_h = get_1d_rotary_pos_embed(dim_h, grid_h, use_real=True)
|
||||
freqs_w = get_1d_rotary_pos_embed(dim_w, grid_w, use_real=True)
|
||||
|
||||
# BroadCast and concatenate temporal and spaial frequencie (height and width) into a 3d tensor
|
||||
def combine_time_height_width(freqs_t, freqs_h, freqs_w):
|
||||
freqs_t = freqs_t[:, None, None, :].expand(
|
||||
-1, grid_size_h, grid_size_w, -1
|
||||
) # temporal_size, grid_size_h, grid_size_w, dim_t
|
||||
freqs_h = freqs_h[None, :, None, :].expand(
|
||||
temporal_size, -1, grid_size_w, -1
|
||||
) # temporal_size, grid_size_h, grid_size_2, dim_h
|
||||
freqs_w = freqs_w[None, None, :, :].expand(
|
||||
temporal_size, grid_size_h, -1, -1
|
||||
) # temporal_size, grid_size_h, grid_size_2, dim_w
|
||||
|
||||
freqs = torch.cat(
|
||||
[freqs_t, freqs_h, freqs_w], dim=-1
|
||||
) # temporal_size, grid_size_h, grid_size_w, (dim_t + dim_h + dim_w)
|
||||
freqs = freqs.view(
|
||||
temporal_size * grid_size_h * grid_size_w, -1
|
||||
) # (temporal_size * grid_size_h * grid_size_w), (dim_t + dim_h + dim_w)
|
||||
return freqs
|
||||
|
||||
t_cos, t_sin = freqs_t # both t_cos and t_sin has shape: temporal_size, dim_t
|
||||
h_cos, h_sin = freqs_h # both h_cos and h_sin has shape: grid_size_h, dim_h
|
||||
w_cos, w_sin = freqs_w # both w_cos and w_sin has shape: grid_size_w, dim_w
|
||||
|
||||
if grid_type == "slice":
|
||||
t_cos, t_sin = t_cos[:temporal_size], t_sin[:temporal_size]
|
||||
h_cos, h_sin = h_cos[:grid_size_h], h_sin[:grid_size_h]
|
||||
w_cos, w_sin = w_cos[:grid_size_w], w_sin[:grid_size_w]
|
||||
|
||||
cos = combine_time_height_width(t_cos, h_cos, w_cos)
|
||||
sin = combine_time_height_width(t_sin, h_sin, w_sin)
|
||||
return cos, sin
|
||||
|
||||
|
||||
# Similar to diffusers.pipelines.hunyuandit.pipeline_hunyuandit.get_resize_crop_region_for_grid
|
||||
def get_resize_crop_region_for_grid(src, tgt_width, tgt_height):
|
||||
@@ -256,21 +177,8 @@ def resize_mask(mask, latent, process_first_frame_only=True):
|
||||
return resized_mask
|
||||
|
||||
|
||||
def add_noise_to_reference_video(image, ratio=None):
|
||||
if ratio is None:
|
||||
sigma = torch.normal(mean=-3.0, std=0.5, size=(image.shape[0],)).to(image.device)
|
||||
sigma = torch.exp(sigma).to(image.dtype)
|
||||
else:
|
||||
sigma = torch.ones((image.shape[0],)).to(image.device, image.dtype) * ratio
|
||||
|
||||
image_noise = torch.randn_like(image) * sigma[:, None, None, None, None]
|
||||
image_noise = torch.where(image==-1, torch.zeros_like(image), image_noise)
|
||||
image = image + image_noise
|
||||
return image
|
||||
|
||||
|
||||
@dataclass
|
||||
class CogVideoXFunPipelineOutput(BaseOutput):
|
||||
class CogVideoX_Fun_PipelineOutput(BaseOutput):
|
||||
r"""
|
||||
Output class for CogVideo pipelines.
|
||||
|
||||
@@ -284,7 +192,7 @@ class CogVideoXFunPipelineOutput(BaseOutput):
|
||||
videos: torch.Tensor
|
||||
|
||||
|
||||
class CogVideoXFunInpaintPipeline(DiffusionPipeline):
|
||||
class CogVideoX_Fun_Pipeline_Inpaint(DiffusionPipeline):
|
||||
r"""
|
||||
Pipeline for text-to-video generation using CogVideoX.
|
||||
|
||||
@@ -308,7 +216,7 @@ class CogVideoXFunInpaintPipeline(DiffusionPipeline):
|
||||
"""
|
||||
|
||||
_optional_components = []
|
||||
model_cpu_offload_seq = "text_encoder->transformer->vae"
|
||||
model_cpu_offload_seq = "text_encoder->vae->transformer->vae"
|
||||
|
||||
_callback_tensor_inputs = [
|
||||
"latents",
|
||||
@@ -536,7 +444,7 @@ class CogVideoXFunInpaintPipeline(DiffusionPipeline):
|
||||
return outputs
|
||||
|
||||
def prepare_mask_latents(
|
||||
self, mask, masked_image, batch_size, height, width, dtype, device, generator, do_classifier_free_guidance, noise_aug_strength
|
||||
self, mask, masked_image, batch_size, height, width, dtype, device, generator, do_classifier_free_guidance
|
||||
):
|
||||
# resize the mask to latents shape as we concatenate the mask to the latents
|
||||
# we do that before converting to dtype to avoid breaking in case we're using cpu_offload
|
||||
@@ -555,8 +463,6 @@ class CogVideoXFunInpaintPipeline(DiffusionPipeline):
|
||||
mask = mask * self.vae.config.scaling_factor
|
||||
|
||||
if masked_image is not None:
|
||||
if self.transformer.config.add_noise_in_inpaint_model:
|
||||
masked_image = add_noise_to_reference_video(masked_image, ratio=noise_aug_strength)
|
||||
masked_image = masked_image.to(device=device, dtype=self.vae.dtype)
|
||||
bs = 1
|
||||
new_mask_pixel_values = []
|
||||
@@ -674,36 +580,19 @@ class CogVideoXFunInpaintPipeline(DiffusionPipeline):
|
||||
) -> Tuple[torch.Tensor, torch.Tensor]:
|
||||
grid_height = height // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
|
||||
grid_width = width // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
|
||||
base_size_width = 720 // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
|
||||
base_size_height = 480 // (self.vae_scale_factor_spatial * self.transformer.config.patch_size)
|
||||
|
||||
p = self.transformer.config.patch_size
|
||||
p_t = self.transformer.config.patch_size_t
|
||||
|
||||
base_size_width = self.transformer.config.sample_width // p
|
||||
base_size_height = self.transformer.config.sample_height // p
|
||||
|
||||
if p_t is None:
|
||||
# CogVideoX 1.0
|
||||
grid_crops_coords = get_resize_crop_region_for_grid(
|
||||
(grid_height, grid_width), base_size_width, base_size_height
|
||||
)
|
||||
freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
|
||||
embed_dim=self.transformer.config.attention_head_dim,
|
||||
crops_coords=grid_crops_coords,
|
||||
grid_size=(grid_height, grid_width),
|
||||
temporal_size=num_frames,
|
||||
)
|
||||
else:
|
||||
# CogVideoX 1.5
|
||||
base_num_frames = (num_frames + p_t - 1) // p_t
|
||||
|
||||
freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
|
||||
embed_dim=self.transformer.config.attention_head_dim,
|
||||
crops_coords=None,
|
||||
grid_size=(grid_height, grid_width),
|
||||
temporal_size=base_num_frames,
|
||||
grid_type="slice",
|
||||
max_size=(base_size_height, base_size_width),
|
||||
)
|
||||
grid_crops_coords = get_resize_crop_region_for_grid(
|
||||
(grid_height, grid_width), base_size_width, base_size_height
|
||||
)
|
||||
freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
|
||||
embed_dim=self.transformer.config.attention_head_dim,
|
||||
crops_coords=grid_crops_coords,
|
||||
grid_size=(grid_height, grid_width),
|
||||
temporal_size=num_frames,
|
||||
use_real=True,
|
||||
)
|
||||
|
||||
freqs_cos = freqs_cos.to(device=device)
|
||||
freqs_sin = freqs_sin.to(device=device)
|
||||
@@ -717,10 +606,6 @@ class CogVideoXFunInpaintPipeline(DiffusionPipeline):
|
||||
def num_timesteps(self):
|
||||
return self._num_timesteps
|
||||
|
||||
@property
|
||||
def attention_kwargs(self):
|
||||
return self._attention_kwargs
|
||||
|
||||
@property
|
||||
def interrupt(self):
|
||||
return self._interrupt
|
||||
@@ -762,13 +647,11 @@ class CogVideoXFunInpaintPipeline(DiffusionPipeline):
|
||||
callback_on_step_end: Optional[
|
||||
Union[Callable[[int, int, Dict], None], PipelineCallback, MultiPipelineCallbacks]
|
||||
] = None,
|
||||
attention_kwargs: Optional[Dict[str, Any]] = None,
|
||||
callback_on_step_end_tensor_inputs: List[str] = ["latents"],
|
||||
max_sequence_length: int = 226,
|
||||
strength: float = 1,
|
||||
noise_aug_strength: float = 0.0563,
|
||||
comfyui_progressbar: bool = False,
|
||||
) -> Union[CogVideoXFunPipelineOutput, Tuple]:
|
||||
) -> Union[CogVideoX_Fun_PipelineOutput, Tuple]:
|
||||
"""
|
||||
Function invoked when calling the pipeline for generation.
|
||||
|
||||
@@ -840,18 +723,21 @@ class CogVideoXFunInpaintPipeline(DiffusionPipeline):
|
||||
Examples:
|
||||
|
||||
Returns:
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoXFunPipelineOutput`] or `tuple`:
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoXFunPipelineOutput`] if `return_dict` is True, otherwise a
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_Fun_PipelineOutput`] or `tuple`:
|
||||
[`~pipelines.cogvideo.pipeline_cogvideox.CogVideoX_Fun_PipelineOutput`] if `return_dict` is True, otherwise a
|
||||
`tuple`. When returning a tuple, the first element is a list with the generated images.
|
||||
"""
|
||||
|
||||
if num_frames > 49:
|
||||
raise ValueError(
|
||||
"The number of frames must be less than 49 for now due to static positional embeddings. This will be updated in the future to remove this limitation."
|
||||
)
|
||||
|
||||
if isinstance(callback_on_step_end, (PipelineCallback, MultiPipelineCallbacks)):
|
||||
callback_on_step_end_tensor_inputs = callback_on_step_end.tensor_inputs
|
||||
|
||||
height = height or self.transformer.config.sample_height * self.vae_scale_factor_spatial
|
||||
width = width or self.transformer.config.sample_width * self.vae_scale_factor_spatial
|
||||
num_frames = num_frames or self.transformer.config.sample_frames
|
||||
|
||||
height = height or self.transformer.config.sample_size * self.vae_scale_factor_spatial
|
||||
width = width or self.transformer.config.sample_size * self.vae_scale_factor_spatial
|
||||
num_videos_per_prompt = 1
|
||||
|
||||
# 1. Check inputs. Raise error if not correct
|
||||
@@ -865,7 +751,6 @@ class CogVideoXFunInpaintPipeline(DiffusionPipeline):
|
||||
negative_prompt_embeds,
|
||||
)
|
||||
self._guidance_scale = guidance_scale
|
||||
self._attention_kwargs = attention_kwargs
|
||||
self._interrupt = False
|
||||
|
||||
# 2. Default call parameters
|
||||
@@ -920,23 +805,6 @@ class CogVideoXFunInpaintPipeline(DiffusionPipeline):
|
||||
else:
|
||||
init_video = None
|
||||
|
||||
# Magvae needs the number of frames to be 4n + 1.
|
||||
local_latent_length = (num_frames - 1) // self.vae_scale_factor_temporal + 1
|
||||
# For CogVideoX 1.5, the latent frames should be clipped to make it divisible by patch_size_t
|
||||
patch_size_t = self.transformer.config.patch_size_t
|
||||
additional_frames = 0
|
||||
if patch_size_t is not None and local_latent_length % patch_size_t != 0:
|
||||
additional_frames = local_latent_length % patch_size_t
|
||||
num_frames -= additional_frames * self.vae_scale_factor_temporal
|
||||
if num_frames <= 0:
|
||||
num_frames = 1
|
||||
if video_length > num_frames:
|
||||
logger.warning("The length of condition video is not right, the latent frames should be clipped to make it divisible by patch_size_t. ")
|
||||
video_length = num_frames
|
||||
video = video[:, :, :video_length]
|
||||
init_video = init_video[:, :, :video_length]
|
||||
mask_video = mask_video[:, :, :video_length]
|
||||
|
||||
num_channels_latents = self.vae.config.latent_channels
|
||||
num_channels_transformer = self.transformer.config.in_channels
|
||||
return_image_latents = num_channels_transformer == num_channels_latents
|
||||
@@ -998,7 +866,6 @@ class CogVideoXFunInpaintPipeline(DiffusionPipeline):
|
||||
device,
|
||||
generator,
|
||||
do_classifier_free_guidance,
|
||||
noise_aug_strength=noise_aug_strength,
|
||||
)
|
||||
mask_latents = resize_mask(1 - mask_condition, masked_video_latents)
|
||||
mask_latents = mask_latents.to(masked_video_latents.device) * self.vae.config.scaling_factor
|
||||
@@ -1133,4 +1000,4 @@ class CogVideoXFunInpaintPipeline(DiffusionPipeline):
|
||||
if not return_dict:
|
||||
video = torch.from_numpy(video)
|
||||
|
||||
return CogVideoXFunPipelineOutput(videos=video)
|
||||
return CogVideoX_Fun_PipelineOutput(videos=video)
|
||||
@@ -111,6 +111,7 @@ class LoRAModule(torch.nn.Module):
|
||||
|
||||
return org_forwarded.to(weight_dtype) + lx.to(weight_dtype) * self.multiplier * scale
|
||||
|
||||
|
||||
def addnet_hash_legacy(b):
|
||||
"""Old model hash used by sd-webui-additional-networks for .safetensors format files"""
|
||||
m = hashlib.sha256()
|
||||
@@ -119,6 +120,7 @@ def addnet_hash_legacy(b):
|
||||
m.update(b.read(0x10000))
|
||||
return m.hexdigest()[0:8]
|
||||
|
||||
|
||||
def addnet_hash_safetensors(b):
|
||||
"""New model hash used by sd-webui-additional-networks for .safetensors format files"""
|
||||
hash_sha256 = hashlib.sha256()
|
||||
@@ -135,6 +137,7 @@ def addnet_hash_safetensors(b):
|
||||
|
||||
return hash_sha256.hexdigest()
|
||||
|
||||
|
||||
def precalculate_safetensors_hashes(tensors, metadata):
|
||||
"""Precalculate the model hashes needed by sd-webui-additional-networks to
|
||||
save time on indexing the model later."""
|
||||
@@ -151,15 +154,10 @@ def precalculate_safetensors_hashes(tensors, metadata):
|
||||
legacy_hash = addnet_hash_legacy(b)
|
||||
return model_hash, legacy_hash
|
||||
|
||||
|
||||
class LoRANetwork(torch.nn.Module):
|
||||
TRANSFORMER_TARGET_REPLACE_MODULE = [
|
||||
"CogVideoXTransformer3DModel", "WanTransformer3DModel", \
|
||||
"Wan2_2Transformer3DModel", "FluxTransformer2DModel", "QwenImageTransformer2DModel", \
|
||||
"Wan2_2Transformer3DModel_Animate", "Wan2_2Transformer3DModel_S2V", "FantasyTalkingTransformer3DModel", \
|
||||
"HunyuanVideoTransformer3DModel", "Flux2Transformer2DModel", "ZImageTransformer2DModel", \
|
||||
"LongCatVideoTransformer3DModel", "TurboWanTransformer3DModel",
|
||||
]
|
||||
TEXT_ENCODER_TARGET_REPLACE_MODULE = ["T5LayerSelfAttention", "T5LayerFF", "BertEncoder", "T5SelfAttention", "T5CrossAttention"]
|
||||
TRANSFORMER_TARGET_REPLACE_MODULE = ["CogVideoXTransformer3DModel"]
|
||||
TEXT_ENCODER_TARGET_REPLACE_MODULE = ["T5LayerSelfAttention", "T5LayerFF", "BertEncoder"]
|
||||
LORA_PREFIX_TRANSFORMER = "lora_unet"
|
||||
LORA_PREFIX_TEXT_ENCODER = "lora_te"
|
||||
def __init__(
|
||||
@@ -171,8 +169,7 @@ class LoRANetwork(torch.nn.Module):
|
||||
alpha: float = 1,
|
||||
dropout: Optional[float] = None,
|
||||
module_class: Type[object] = LoRAModule,
|
||||
skip_name: str = None,
|
||||
target_name: str = None,
|
||||
add_lora_in_attn_temporal: bool = False,
|
||||
varbose: Optional[bool] = False,
|
||||
) -> None:
|
||||
super().__init__()
|
||||
@@ -205,18 +202,10 @@ class LoRANetwork(torch.nn.Module):
|
||||
is_conv2d = child_module.__class__.__name__ == "Conv2d" or child_module.__class__.__name__ == "LoRACompatibleConv"
|
||||
is_conv2d_1x1 = is_conv2d and child_module.kernel_size == (1, 1)
|
||||
|
||||
skip_names = skip_name.split(',') if skip_name is not None else []
|
||||
target_names = target_name.split(',') if target_name is not None else []
|
||||
|
||||
skip_names = [name.strip() for name in skip_names if name.strip()]
|
||||
target_names = [name.strip() for name in target_names if name.strip()]
|
||||
|
||||
if skip_names and any(skip_n in child_name for skip_n in skip_names):
|
||||
continue
|
||||
|
||||
if target_names and not any(target_n in child_name for target_n in target_names):
|
||||
continue
|
||||
|
||||
if not add_lora_in_attn_temporal:
|
||||
if "attn_temporal" in child_name:
|
||||
continue
|
||||
|
||||
if is_linear or is_conv2d:
|
||||
lora_name = prefix + "." + name + "." + child_name
|
||||
lora_name = lora_name.replace(".", "_")
|
||||
@@ -357,8 +346,7 @@ def create_network(
|
||||
text_encoder: Union[T5EncoderModel, List[T5EncoderModel]],
|
||||
transformer,
|
||||
neuron_dropout: Optional[float] = None,
|
||||
skip_name: str = None,
|
||||
target_name: str = None,
|
||||
add_lora_in_attn_temporal: bool = False,
|
||||
**kwargs,
|
||||
):
|
||||
if network_dim is None:
|
||||
@@ -373,75 +361,23 @@ def create_network(
|
||||
lora_dim=network_dim,
|
||||
alpha=network_alpha,
|
||||
dropout=neuron_dropout,
|
||||
skip_name=skip_name,
|
||||
target_name=target_name,
|
||||
add_lora_in_attn_temporal=add_lora_in_attn_temporal,
|
||||
varbose=True,
|
||||
)
|
||||
return network
|
||||
|
||||
def convert_peft_lora_to_kohya_lora(state_dict):
|
||||
new_state_dict = {}
|
||||
for key, value in state_dict.items():
|
||||
if "diffusion_model." in key:
|
||||
key = key.replace("diffusion_model.", "")
|
||||
if "lora_unet__" not in key:
|
||||
key = "lora_unet__" + key
|
||||
key = key.replace(".lora_A.default.", ".lora_down.")
|
||||
key = key.replace(".lora_B.default.", ".lora_up.")
|
||||
key = key.replace(".lora_A.", ".lora_down.")
|
||||
key = key.replace(".lora_B.", ".lora_up.")
|
||||
key = key.replace(".", "_")
|
||||
if key.endswith("_lora_up_weight"):
|
||||
key = key[:-15] + ".lora_up.weight"
|
||||
if key.endswith("_lora_down_weight"):
|
||||
key = key[:-17] + ".lora_down.weight"
|
||||
new_state_dict[key] = value
|
||||
return new_state_dict
|
||||
|
||||
def merge_lora(pipeline, lora_path, multiplier, device='cpu', dtype=torch.float32, state_dict=None, transformer_only=False, sub_transformer_name="transformer"):
|
||||
if lora_path is None:
|
||||
return pipeline
|
||||
|
||||
def merge_lora(pipeline, lora_path, multiplier, device='cpu', dtype=torch.float32, state_dict=None, transformer_only=False):
|
||||
LORA_PREFIX_TRANSFORMER = "lora_unet"
|
||||
LORA_PREFIX_TEXT_ENCODER = "lora_te"
|
||||
if state_dict is None:
|
||||
state_dict = load_file(lora_path)
|
||||
state_dict = load_file(lora_path, device=device)
|
||||
else:
|
||||
state_dict = state_dict
|
||||
updates = defaultdict(dict)
|
||||
for key, value in state_dict.items():
|
||||
if "diffusion_model." in key:
|
||||
key = key.replace("diffusion_model.", "")
|
||||
if "lora_unet__" not in key:
|
||||
key = "lora_unet__" + key
|
||||
key = key.replace(".", "_")
|
||||
if key.endswith("_lora_up_weight"):
|
||||
key = key[:-15] + ".lora_up.weight"
|
||||
if key.endswith("_lora_down_weight"):
|
||||
key = key[:-17] + ".lora_down.weight"
|
||||
if key.endswith("_lora_A_default_weight"):
|
||||
key = key[:-22] + ".lora_A.weight"
|
||||
if key.endswith("_lora_B_default_weight"):
|
||||
key = key[:-22] + ".lora_B.weight"
|
||||
if key.endswith("_lora_A_weight"):
|
||||
key = key[:-14] + ".lora_A.weight"
|
||||
if key.endswith("_lora_B_weight"):
|
||||
key = key[:-14] + ".lora_B.weight"
|
||||
if key.endswith("_alpha"):
|
||||
key = key[:-6] + ".alpha"
|
||||
key = key.replace(".lora_A.default.", ".lora_down.")
|
||||
key = key.replace(".lora_B.default.", ".lora_up.")
|
||||
key = key.replace(".lora_A.", ".lora_down.")
|
||||
key = key.replace(".lora_B.", ".lora_up.")
|
||||
layer, elem = key.split('.', 1)
|
||||
updates[layer][elem] = value
|
||||
|
||||
sequential_cpu_offload_flag = False
|
||||
if pipeline.transformer.device == torch.device(type="meta"):
|
||||
pipeline.remove_all_hooks()
|
||||
sequential_cpu_offload_flag = True
|
||||
offload_device = pipeline._offload_device
|
||||
|
||||
for layer, elems in updates.items():
|
||||
|
||||
if "lora_te" in layer:
|
||||
@@ -452,128 +388,53 @@ def merge_lora(pipeline, lora_path, multiplier, device='cpu', dtype=torch.float3
|
||||
curr_layer = pipeline.text_encoder
|
||||
else:
|
||||
layer_infos = layer.split(LORA_PREFIX_TRANSFORMER + "_")[-1].split("_")
|
||||
curr_layer = getattr(pipeline, sub_transformer_name)
|
||||
curr_layer = pipeline.transformer
|
||||
|
||||
try:
|
||||
curr_layer = curr_layer.__getattr__("_".join(layer_infos[1:]))
|
||||
except Exception:
|
||||
temp_name = layer_infos.pop(0)
|
||||
temp_name = layer_infos.pop(0)
|
||||
while len(layer_infos) > -1:
|
||||
try:
|
||||
while len(layer_infos) > -1:
|
||||
try:
|
||||
curr_layer = curr_layer.__getattr__(temp_name + "_" + "_".join(layer_infos))
|
||||
break
|
||||
except Exception:
|
||||
try:
|
||||
curr_layer = curr_layer.__getattr__(temp_name)
|
||||
if len(layer_infos) > 0:
|
||||
temp_name = layer_infos.pop(0)
|
||||
elif len(layer_infos) == 0:
|
||||
break
|
||||
except Exception:
|
||||
if len(layer_infos) == 0:
|
||||
print(f'Error loading layer in front search: {layer}. Try it in back search.')
|
||||
if len(temp_name) > 0:
|
||||
temp_name += "_" + layer_infos.pop(0)
|
||||
else:
|
||||
temp_name = layer_infos.pop(0)
|
||||
curr_layer = curr_layer.__getattr__(temp_name)
|
||||
if len(layer_infos) > 0:
|
||||
temp_name = layer_infos.pop(0)
|
||||
elif len(layer_infos) == 0:
|
||||
break
|
||||
except Exception:
|
||||
if "lora_te" in layer:
|
||||
if transformer_only:
|
||||
continue
|
||||
else:
|
||||
layer_infos = layer.split(LORA_PREFIX_TEXT_ENCODER + "_")[-1].split("_")
|
||||
curr_layer = pipeline.text_encoder
|
||||
if len(layer_infos) == 0:
|
||||
print('Error loading layer')
|
||||
if len(temp_name) > 0:
|
||||
temp_name += "_" + layer_infos.pop(0)
|
||||
else:
|
||||
layer_infos = layer.split(LORA_PREFIX_TRANSFORMER + "_")[-1].split("_")
|
||||
curr_layer = getattr(pipeline, sub_transformer_name)
|
||||
temp_name = layer_infos.pop(0)
|
||||
|
||||
len_layer_infos = len(layer_infos)
|
||||
start_index = 0 if len_layer_infos >= 1 and len(layer_infos[0]) > 0 else 1
|
||||
end_indx = len_layer_infos
|
||||
|
||||
error_flag = False if len_layer_infos >= 1 else True
|
||||
while start_index < len_layer_infos:
|
||||
try:
|
||||
if start_index >= end_indx:
|
||||
print(f'Error loading layer in back search: {layer}')
|
||||
error_flag = True
|
||||
break
|
||||
curr_layer = curr_layer.__getattr__("_".join(layer_infos[start_index:end_indx]))
|
||||
start_index = end_indx
|
||||
end_indx = len_layer_infos
|
||||
except Exception:
|
||||
end_indx -= 1
|
||||
if error_flag:
|
||||
continue
|
||||
|
||||
origin_dtype = curr_layer.weight.data.dtype
|
||||
origin_device = curr_layer.weight.data.device
|
||||
|
||||
curr_layer = curr_layer.to(device, dtype)
|
||||
weight_up = elems['lora_up.weight'].to(device, dtype)
|
||||
weight_down = elems['lora_down.weight'].to(device, dtype)
|
||||
|
||||
weight_up = elems['lora_up.weight'].to(dtype)
|
||||
weight_down = elems['lora_down.weight'].to(dtype)
|
||||
if 'alpha' in elems.keys():
|
||||
alpha = elems['alpha'].item() / weight_up.shape[1]
|
||||
else:
|
||||
alpha = 1.0
|
||||
|
||||
curr_layer.weight.data = curr_layer.weight.data.to(device)
|
||||
if len(weight_up.shape) == 4:
|
||||
curr_layer.weight.data += multiplier * alpha * torch.mm(
|
||||
weight_up.squeeze(3).squeeze(2), weight_down.squeeze(3).squeeze(2)
|
||||
).unsqueeze(2).unsqueeze(3)
|
||||
curr_layer.weight.data += multiplier * alpha * torch.mm(weight_up.squeeze(3).squeeze(2),
|
||||
weight_down.squeeze(3).squeeze(2)).unsqueeze(
|
||||
2).unsqueeze(3)
|
||||
else:
|
||||
curr_layer.weight.data += multiplier * alpha * torch.mm(weight_up, weight_down)
|
||||
curr_layer = curr_layer.to(origin_device, origin_dtype)
|
||||
|
||||
if sequential_cpu_offload_flag:
|
||||
pipeline.enable_sequential_cpu_offload(device=offload_device)
|
||||
return pipeline
|
||||
|
||||
# TODO: Refactor with merge_lora.
|
||||
def unmerge_lora(pipeline, lora_path, multiplier=1, device="cpu", dtype=torch.float32, sub_transformer_name="transformer"):
|
||||
if lora_path is None:
|
||||
return pipeline
|
||||
|
||||
def unmerge_lora(pipeline, lora_path, multiplier=1, device="cpu", dtype=torch.float32):
|
||||
"""Unmerge state_dict in LoRANetwork from the pipeline in diffusers."""
|
||||
LORA_PREFIX_UNET = "lora_unet"
|
||||
LORA_PREFIX_TEXT_ENCODER = "lora_te"
|
||||
state_dict = load_file(lora_path)
|
||||
state_dict = load_file(lora_path, device=device)
|
||||
|
||||
updates = defaultdict(dict)
|
||||
for key, value in state_dict.items():
|
||||
if "diffusion_model." in key:
|
||||
key = key.replace("diffusion_model.", "")
|
||||
if "lora_unet__" not in key:
|
||||
key = "lora_unet__" + key
|
||||
key = key.replace(".", "_")
|
||||
if key.endswith("_lora_up_weight"):
|
||||
key = key[:-15] + ".lora_up.weight"
|
||||
if key.endswith("_lora_down_weight"):
|
||||
key = key[:-17] + ".lora_down.weight"
|
||||
if key.endswith("_lora_A_default_weight"):
|
||||
key = key[:-22] + ".lora_A.weight"
|
||||
if key.endswith("_lora_B_default_weight"):
|
||||
key = key[:-22] + ".lora_B.weight"
|
||||
if key.endswith("_lora_A_weight"):
|
||||
key = key[:-14] + ".lora_A.weight"
|
||||
if key.endswith("_lora_B_weight"):
|
||||
key = key[:-14] + ".lora_B.weight"
|
||||
if key.endswith("_alpha"):
|
||||
key = key[:-6] + ".alpha"
|
||||
key = key.replace(".lora_A.default.", ".lora_down.")
|
||||
key = key.replace(".lora_B.default.", ".lora_up.")
|
||||
key = key.replace(".lora_A.", ".lora_down.")
|
||||
key = key.replace(".lora_B.", ".lora_up.")
|
||||
layer, elem = key.split('.', 1)
|
||||
updates[layer][elem] = value
|
||||
|
||||
sequential_cpu_offload_flag = False
|
||||
if pipeline.transformer.device == torch.device(type="meta"):
|
||||
pipeline.remove_all_hooks()
|
||||
sequential_cpu_offload_flag = True
|
||||
|
||||
for layer, elems in updates.items():
|
||||
|
||||
if "lora_te" in layer:
|
||||
@@ -581,78 +442,36 @@ def unmerge_lora(pipeline, lora_path, multiplier=1, device="cpu", dtype=torch.fl
|
||||
curr_layer = pipeline.text_encoder
|
||||
else:
|
||||
layer_infos = layer.split(LORA_PREFIX_UNET + "_")[-1].split("_")
|
||||
curr_layer = getattr(pipeline, sub_transformer_name)
|
||||
curr_layer = pipeline.transformer
|
||||
|
||||
try:
|
||||
curr_layer = curr_layer.__getattr__("_".join(layer_infos[1:]))
|
||||
except Exception:
|
||||
temp_name = layer_infos.pop(0)
|
||||
temp_name = layer_infos.pop(0)
|
||||
while len(layer_infos) > -1:
|
||||
try:
|
||||
while len(layer_infos) > -1:
|
||||
try:
|
||||
curr_layer = curr_layer.__getattr__(temp_name + "_" + "_".join(layer_infos))
|
||||
break
|
||||
except Exception:
|
||||
try:
|
||||
curr_layer = curr_layer.__getattr__(temp_name)
|
||||
if len(layer_infos) > 0:
|
||||
temp_name = layer_infos.pop(0)
|
||||
elif len(layer_infos) == 0:
|
||||
break
|
||||
except Exception:
|
||||
if len(layer_infos) == 0:
|
||||
print(f'Error loading layer in front search: {layer}. Try it in back search.')
|
||||
if len(temp_name) > 0:
|
||||
temp_name += "_" + layer_infos.pop(0)
|
||||
else:
|
||||
temp_name = layer_infos.pop(0)
|
||||
curr_layer = curr_layer.__getattr__(temp_name)
|
||||
if len(layer_infos) > 0:
|
||||
temp_name = layer_infos.pop(0)
|
||||
elif len(layer_infos) == 0:
|
||||
break
|
||||
except Exception:
|
||||
if "lora_te" in layer:
|
||||
layer_infos = layer.split(LORA_PREFIX_TEXT_ENCODER + "_")[-1].split("_")
|
||||
curr_layer = pipeline.text_encoder
|
||||
if len(layer_infos) == 0:
|
||||
print('Error loading layer')
|
||||
if len(temp_name) > 0:
|
||||
temp_name += "_" + layer_infos.pop(0)
|
||||
else:
|
||||
layer_infos = layer.split(LORA_PREFIX_UNET + "_")[-1].split("_")
|
||||
curr_layer = getattr(pipeline, sub_transformer_name)
|
||||
len_layer_infos = len(layer_infos)
|
||||
temp_name = layer_infos.pop(0)
|
||||
|
||||
start_index = 0 if len_layer_infos >= 1 and len(layer_infos[0]) > 0 else 1
|
||||
end_indx = len_layer_infos
|
||||
|
||||
error_flag = False if len_layer_infos >= 1 else True
|
||||
while start_index < len_layer_infos:
|
||||
try:
|
||||
if start_index >= end_indx:
|
||||
print(f'Error loading layer in back search: {layer}')
|
||||
error_flag = True
|
||||
break
|
||||
curr_layer = curr_layer.__getattr__("_".join(layer_infos[start_index:end_indx]))
|
||||
start_index = end_indx
|
||||
end_indx = len_layer_infos
|
||||
except Exception:
|
||||
end_indx -= 1
|
||||
if error_flag:
|
||||
continue
|
||||
|
||||
origin_dtype = curr_layer.weight.data.dtype
|
||||
origin_device = curr_layer.weight.data.device
|
||||
|
||||
curr_layer = curr_layer.to(device, dtype)
|
||||
weight_up = elems['lora_up.weight'].to(device, dtype)
|
||||
weight_down = elems['lora_down.weight'].to(device, dtype)
|
||||
|
||||
weight_up = elems['lora_up.weight'].to(dtype)
|
||||
weight_down = elems['lora_down.weight'].to(dtype)
|
||||
if 'alpha' in elems.keys():
|
||||
alpha = elems['alpha'].item() / weight_up.shape[1]
|
||||
else:
|
||||
alpha = 1.0
|
||||
|
||||
curr_layer.weight.data = curr_layer.weight.data.to(device)
|
||||
if len(weight_up.shape) == 4:
|
||||
curr_layer.weight.data -= multiplier * alpha * torch.mm(
|
||||
weight_up.squeeze(3).squeeze(2), weight_down.squeeze(3).squeeze(2)
|
||||
).unsqueeze(2).unsqueeze(3)
|
||||
curr_layer.weight.data -= multiplier * alpha * torch.mm(weight_up.squeeze(3).squeeze(2),
|
||||
weight_down.squeeze(3).squeeze(2)).unsqueeze(2).unsqueeze(3)
|
||||
else:
|
||||
curr_layer.weight.data -= multiplier * alpha * torch.mm(weight_up, weight_down)
|
||||
curr_layer = curr_layer.to(origin_device, origin_dtype)
|
||||
|
||||
if sequential_cpu_offload_flag:
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
return pipeline
|
||||
return pipeline
|
||||
@@ -0,0 +1,189 @@
|
||||
import os
|
||||
import gc
|
||||
import imageio
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchvision
|
||||
import cv2
|
||||
from einops import rearrange
|
||||
from PIL import Image
|
||||
|
||||
def get_width_and_height_from_image_and_base_resolution(image, base_resolution):
|
||||
target_pixels = int(base_resolution) * int(base_resolution)
|
||||
original_width, original_height = Image.open(image).size
|
||||
ratio = (target_pixels / (original_width * original_height)) ** 0.5
|
||||
width_slider = round(original_width * ratio)
|
||||
height_slider = round(original_height * ratio)
|
||||
return height_slider, width_slider
|
||||
|
||||
def color_transfer(sc, dc):
|
||||
"""
|
||||
Transfer color distribution from of sc, referred to dc.
|
||||
|
||||
Args:
|
||||
sc (numpy.ndarray): input image to be transfered.
|
||||
dc (numpy.ndarray): reference image
|
||||
|
||||
Returns:
|
||||
numpy.ndarray: Transferred color distribution on the sc.
|
||||
"""
|
||||
|
||||
def get_mean_and_std(img):
|
||||
x_mean, x_std = cv2.meanStdDev(img)
|
||||
x_mean = np.hstack(np.around(x_mean, 2))
|
||||
x_std = np.hstack(np.around(x_std, 2))
|
||||
return x_mean, x_std
|
||||
|
||||
sc = cv2.cvtColor(sc, cv2.COLOR_RGB2LAB)
|
||||
s_mean, s_std = get_mean_and_std(sc)
|
||||
dc = cv2.cvtColor(dc, cv2.COLOR_RGB2LAB)
|
||||
t_mean, t_std = get_mean_and_std(dc)
|
||||
img_n = ((sc - s_mean) * (t_std / s_std)) + t_mean
|
||||
np.putmask(img_n, img_n > 255, 255)
|
||||
np.putmask(img_n, img_n < 0, 0)
|
||||
dst = cv2.cvtColor(cv2.convertScaleAbs(img_n), cv2.COLOR_LAB2RGB)
|
||||
return dst
|
||||
|
||||
def save_videos_grid(videos: torch.Tensor, path: str, rescale=False, n_rows=6, fps=12, imageio_backend=True, color_transfer_post_process=False):
|
||||
videos = rearrange(videos, "b c t h w -> t b c h w")
|
||||
outputs = []
|
||||
for x in videos:
|
||||
x = torchvision.utils.make_grid(x, nrow=n_rows)
|
||||
x = x.transpose(0, 1).transpose(1, 2).squeeze(-1)
|
||||
if rescale:
|
||||
x = (x + 1.0) / 2.0 # -1,1 -> 0,1
|
||||
x = (x * 255).numpy().astype(np.uint8)
|
||||
outputs.append(Image.fromarray(x))
|
||||
|
||||
if color_transfer_post_process:
|
||||
for i in range(1, len(outputs)):
|
||||
outputs[i] = Image.fromarray(color_transfer(np.uint8(outputs[i]), np.uint8(outputs[0])))
|
||||
|
||||
os.makedirs(os.path.dirname(path), exist_ok=True)
|
||||
if imageio_backend:
|
||||
if path.endswith("mp4"):
|
||||
imageio.mimsave(path, outputs, fps=fps)
|
||||
else:
|
||||
imageio.mimsave(path, outputs, duration=(1000 * 1/fps))
|
||||
else:
|
||||
if path.endswith("mp4"):
|
||||
path = path.replace('.mp4', '.gif')
|
||||
outputs[0].save(path, format='GIF', append_images=outputs, save_all=True, duration=100, loop=0)
|
||||
|
||||
def get_image_to_video_latent(validation_image_start, validation_image_end, video_length, sample_size):
|
||||
if validation_image_start is not None and validation_image_end is not None:
|
||||
if type(validation_image_start) is str and os.path.isfile(validation_image_start):
|
||||
image_start = clip_image = Image.open(validation_image_start).convert("RGB")
|
||||
image_start = image_start.resize([sample_size[1], sample_size[0]])
|
||||
clip_image = clip_image.resize([sample_size[1], sample_size[0]])
|
||||
else:
|
||||
image_start = clip_image = validation_image_start
|
||||
image_start = [_image_start.resize([sample_size[1], sample_size[0]]) for _image_start in image_start]
|
||||
clip_image = [_clip_image.resize([sample_size[1], sample_size[0]]) for _clip_image in clip_image]
|
||||
|
||||
if type(validation_image_end) is str and os.path.isfile(validation_image_end):
|
||||
image_end = Image.open(validation_image_end).convert("RGB")
|
||||
image_end = image_end.resize([sample_size[1], sample_size[0]])
|
||||
else:
|
||||
image_end = validation_image_end
|
||||
image_end = [_image_end.resize([sample_size[1], sample_size[0]]) for _image_end in image_end]
|
||||
|
||||
if type(image_start) is list:
|
||||
clip_image = clip_image[0]
|
||||
start_video = torch.cat(
|
||||
[torch.from_numpy(np.array(_image_start)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0) for _image_start in image_start],
|
||||
dim=2
|
||||
)
|
||||
input_video = torch.tile(start_video[:, :, :1], [1, 1, video_length, 1, 1])
|
||||
input_video[:, :, :len(image_start)] = start_video
|
||||
|
||||
input_video_mask = torch.zeros_like(input_video[:, :1])
|
||||
input_video_mask[:, :, len(image_start):] = 255
|
||||
else:
|
||||
input_video = torch.tile(
|
||||
torch.from_numpy(np.array(image_start)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0),
|
||||
[1, 1, video_length, 1, 1]
|
||||
)
|
||||
input_video_mask = torch.zeros_like(input_video[:, :1])
|
||||
input_video_mask[:, :, 3:] = 255
|
||||
|
||||
if type(image_end) is list:
|
||||
image_end = [_image_end.resize(image_start[0].size if type(image_start) is list else image_start.size) for _image_end in image_end]
|
||||
end_video = torch.cat(
|
||||
[torch.from_numpy(np.array(_image_end)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0) for _image_end in image_end],
|
||||
dim=2
|
||||
)
|
||||
input_video[:, :, -len(end_video):] = end_video
|
||||
|
||||
input_video_mask[:, :, -len(image_end):] = 0
|
||||
else:
|
||||
image_end = image_end.resize(image_start[0].size if type(image_start) is list else image_start.size)
|
||||
input_video[:, :, -3:] = torch.from_numpy(np.array(image_end)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0)
|
||||
input_video_mask[:, :, -3:] = 0
|
||||
|
||||
input_video = input_video / 255
|
||||
|
||||
elif validation_image_start is not None:
|
||||
if type(validation_image_start) is str and os.path.isfile(validation_image_start):
|
||||
image_start = clip_image = Image.open(validation_image_start).convert("RGB")
|
||||
image_start = image_start.resize([sample_size[1], sample_size[0]])
|
||||
clip_image = clip_image.resize([sample_size[1], sample_size[0]])
|
||||
else:
|
||||
image_start = clip_image = validation_image_start
|
||||
image_start = [_image_start.resize([sample_size[1], sample_size[0]]) for _image_start in image_start]
|
||||
clip_image = [_clip_image.resize([sample_size[1], sample_size[0]]) for _clip_image in clip_image]
|
||||
image_end = None
|
||||
|
||||
if type(image_start) is list:
|
||||
clip_image = clip_image[0]
|
||||
start_video = torch.cat(
|
||||
[torch.from_numpy(np.array(_image_start)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0) for _image_start in image_start],
|
||||
dim=2
|
||||
)
|
||||
input_video = torch.tile(start_video[:, :, :1], [1, 1, video_length, 1, 1])
|
||||
input_video[:, :, :len(image_start)] = start_video
|
||||
input_video = input_video / 255
|
||||
|
||||
input_video_mask = torch.zeros_like(input_video[:, :1])
|
||||
input_video_mask[:, :, len(image_start):] = 255
|
||||
else:
|
||||
input_video = torch.tile(
|
||||
torch.from_numpy(np.array(image_start)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0),
|
||||
[1, 1, video_length, 1, 1]
|
||||
) / 255
|
||||
input_video_mask = torch.zeros_like(input_video[:, :1])
|
||||
input_video_mask[:, :, 3:, ] = 255
|
||||
else:
|
||||
image_start = None
|
||||
image_end = None
|
||||
input_video = torch.zeros([1, 3, video_length, sample_size[0], sample_size[1]])
|
||||
input_video_mask = torch.ones([1, 1, video_length, sample_size[0], sample_size[1]]) * 255
|
||||
clip_image = None
|
||||
|
||||
del image_start
|
||||
del image_end
|
||||
gc.collect()
|
||||
|
||||
return input_video, input_video_mask, clip_image
|
||||
|
||||
def get_video_to_video_latent(input_video_path, video_length, sample_size):
|
||||
if type(input_video_path) is str:
|
||||
cap = cv2.VideoCapture(input_video_path)
|
||||
input_video = []
|
||||
while True:
|
||||
ret, frame = cap.read()
|
||||
if not ret:
|
||||
break
|
||||
frame = cv2.resize(frame, (sample_size[1], sample_size[0]))
|
||||
input_video.append(cv2.cvtColor(frame, cv2.COLOR_BGR2RGB))
|
||||
cap.release()
|
||||
else:
|
||||
input_video = input_video_path
|
||||
|
||||
input_video = torch.from_numpy(np.array(input_video))[:video_length]
|
||||
input_video = input_video.permute([3, 0, 1, 2]).unsqueeze(0) / 255
|
||||
|
||||
input_video_mask = torch.zeros_like(input_video[:, :1])
|
||||
input_video_mask[:, :, :] = 255
|
||||
|
||||
return input_video, input_video_mask, None
|
||||
@@ -1,7 +1,7 @@
|
||||
# Video Caption
|
||||
English | [简体中文](./README_zh-CN.md)
|
||||
|
||||
The folder contains codes for dataset preprocessing (i.e., video splitting, filtering, and recaptioning), and beautiful prompt used by EasyAnimate.
|
||||
The folder contains codes for dataset preprocessing (i.e., video splitting, filtering, and recaptioning), and beautiful prompt used by CogVideoX-Fun.
|
||||
The entire process supports distributed parallel processing, capable of handling large-scale datasets.
|
||||
|
||||
Meanwhile, we are collaborating with [Data-Juicer](https://github.com/modelscope/data-juicer/blob/main/docs/DJ_SORA.md),
|
||||
@@ -17,7 +17,7 @@ allowing you to easily perform video data processing on [Aliyun PAI-DLC](https:/
|
||||
- [Video Splitting](#video-splitting)
|
||||
- [Video Filtering](#video-filtering)
|
||||
- [Video Recaptioning](#video-recaptioning)
|
||||
- [Beautiful Prompt (For EasyAnimate Inference)](#beautiful-prompt-for-easyanimate-inference)
|
||||
- [Beautiful Prompt (For CogVideoX-Fun Inference)](#beautiful-prompt-for-cogvideox-inference)
|
||||
- [Batched Inference](#batched-inference)
|
||||
- [OpenAI Server](#openai-server)
|
||||
|
||||
@@ -27,18 +27,21 @@ allowing you to easily perform video data processing on [Aliyun PAI-DLC](https:/
|
||||
AliyunDSW or Docker is recommended to setup the environment, please refer to [Quick Start](../../README.md#quick-start).
|
||||
You can also refer to the image build process in the [Dockerfile](../../Dockerfile.ds) to configure the conda environment and other dependencies locally.
|
||||
|
||||
Since the video recaptioning depends on [llm-awq](https://github.com/mit-han-lab/llm-awq) for faster and memory efficient inference,
|
||||
the minimum GPU requirment should be RTX 3060 or A2 (CUDA Compute Capability >= 8.0).
|
||||
|
||||
```shell
|
||||
# pull image
|
||||
docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:easyanimate
|
||||
docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# enter image
|
||||
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:easyanimate
|
||||
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# clone code
|
||||
git clone https://github.com/aigc-apps/EasyAnimate.git
|
||||
git clone https://github.com/aigc-apps/CogVideoX-Fun.git
|
||||
|
||||
# enter video_caption
|
||||
cd EasyAnimate/easyanimate/video_caption
|
||||
cd CogVideoX-Fun/cogvideox/video_caption
|
||||
```
|
||||
|
||||
### Data Preprocessing
|
||||
@@ -55,7 +58,7 @@ Taking Panda-70M as an example, the entire dataset directory structure is shown
|
||||
```
|
||||
|
||||
#### Video Splitting
|
||||
EasyAnimate utilizes [PySceneDetect](https://github.com/Breakthrough/PySceneDetect) to identify scene changes within the video
|
||||
CogVideoX-Fun utilizes [PySceneDetect](https://github.com/Breakthrough/PySceneDetect) to identify scene changes within the video
|
||||
and performs video splitting via FFmpeg based on certain threshold values to ensure consistency of the video clip.
|
||||
Video clips shorter than 3 seconds will be discarded, and those longer than 10 seconds will be splitted recursively.
|
||||
|
||||
@@ -64,14 +67,12 @@ After running
|
||||
```shell
|
||||
sh scripts/stage_1_video_splitting.sh
|
||||
```
|
||||
the video clips are obtained in `easyanimate/video_caption/datasets/panda_70m/videos_clips/data/`.
|
||||
the video clips are obtained in `cogvideox/video_caption/datasets/panda_70m/videos_clips/data/`.
|
||||
|
||||
#### Video Filtering
|
||||
Based on the videos obtained in the previous step, EasyAnimate provides a simple yet effective pipeline to filter out high-quality videos for recaptioning.
|
||||
Based on the videos obtained in the previous step, CogVideoX-Fun provides a simple yet effective pipeline to filter out high-quality videos for recaptioning.
|
||||
The overall process is as follows:
|
||||
|
||||
- Scene transition filtering: Filter out videos with scene transition introduced by missing or superfluous splitting of PySceneDetect by calculating the semantic similarity
|
||||
accoss the beginning frame, the last frame, and the keyframes via [CLIP](https://github.com/openai/CLIP) or [DINOv2](https://github.com/facebookresearch/dinov2).
|
||||
- Aesthetic filtering: Filter out videos with poor content (blurry, dim, etc.) by calculating the average aesthetic score of uniformly sampled 4 frames via [aesthetic-predictor-v2-5](https://github.com/discus0434/aesthetic-predictor-v2-5).
|
||||
- Text filtering: Use [EasyOCR](https://github.com/JaidedAI/EasyOCR) to calculate the text area proportion of the middle frame to filter out videos with a large area of text.
|
||||
- Motion filtering: Calculate interframe optical flow differences to filter out videos that move too slowly or too quickly.
|
||||
@@ -81,25 +82,23 @@ After running
|
||||
```shell
|
||||
sh scripts/stage_2_video_filtering.sh
|
||||
```
|
||||
the semantic consistency score, aesthetic score, text score, and motion score of videos will be saved
|
||||
in the corresponding meta files in the folder `easyanimate/video_caption/datasets/panda_70m/videos_clips/`.
|
||||
the aesthetic score, text score, and motion score of videos will be saved in the corresponding meta files in the folder `cogvideox/video_caption/datasets/panda_70m/videos_clips/`.
|
||||
|
||||
> [!NOTE]
|
||||
> The computation of semantic consistency score depends on the [openai/clip-vit-large-patch14-336](https://huggingface.co/openai/clip-vit-large-patch14-336).
|
||||
Meanwhile, the aesthetic score depends on the [google/siglip-so400m-patch14-384 model](https://huggingface.co/google/siglip-so400m-patch14-384).
|
||||
> The computation of the aesthetic score depends on the [google/siglip-so400m-patch14-384 model](https://huggingface.co/google/siglip-so400m-patch14-384).
|
||||
Please run `HF_ENDPOINT=https://hf-mirror.com sh scripts/stage_2_video_filtering.sh` if you cannot access to huggingface.com.
|
||||
|
||||
|
||||
#### Video Recaptioning
|
||||
After obtaining the aboved high-quality filtered videos, EasyAnimate utilizes [InternVL2](https://internvl.readthedocs.io/en/latest/internvl2.0/introduction.html) to perform video recaptioning.
|
||||
Subsequently, the recaptioning results are rewritten by LLMs to better meet with the requirements of video generation tasks.
|
||||
Finally, an advanced [VideoCLIP-XL](https://arxiv.org/abs/2410.00741) model is used to filter out (video, long caption) pairs with poor alignment, resulting in the final training dataset.
|
||||
After obtaining the aboved high-quality filtered videos, CogVideoX-Fun utilizes [VILA1.5](https://github.com/NVlabs/VILA) to perform video recaptioning.
|
||||
Subsequently, the recaptioning results are rewritten by LLMs to better meet with the requirements of video generation tasks.
|
||||
Finally, an advanced VideoCLIPXL model is developed to filter out video-caption pairs with poor alignment, resulting in the final training dataset.
|
||||
|
||||
Please download the video caption model from [InternVL2](https://huggingface.co/collections/OpenGVLab/internvl-20-667d3961ab5eb12c7ed1463e) of the appropriate size based on the GPU memory of your machine.
|
||||
For A100 with 40G VRAM, you can download [InternVL2-40B-AWQ](https://huggingface.co/OpenGVLab/InternVL2-40B-AWQ) by running
|
||||
Please download the video caption model from [VILA1.5](https://huggingface.co/collections/Efficient-Large-Model/vila-on-pre-training-for-visual-language-models-65d8022a3a52cd9bcd62698e) of the appropriate size based on the GPU memory of your machine.
|
||||
For A100 with 40G VRAM, you can download [VILA1.5-40b-AWQ](https://huggingface.co/Efficient-Large-Model/VILA1.5-40b-AWQ) by running
|
||||
```shell
|
||||
# Add HF_ENDPOINT=https://hf-mirror.com before the command if you cannot access to huggingface.com
|
||||
huggingface-cli download OpenGVLab/InternVL2-40B-AWQ --local-dir-use-symlinks False --local-dir /PATH/TO/INTERNVL2_MODEL
|
||||
huggingface-cli download Efficient-Large-Model/VILA1.5-40b-AWQ --local-dir-use-symlinks False --local-dir /PATH/TO/VILA_MODEL
|
||||
```
|
||||
|
||||
Optionally, you can prepare local LLMs to rewrite the recaption results.
|
||||
@@ -112,18 +111,18 @@ huggingface-cli download NousResearch/Meta-Llama-3-8B-Instruct --local-dir-use-s
|
||||
The entire workflow of video recaption is in the [stage_3_video_recaptioning.sh](./scripts/stage_3_video_recaptioning.sh).
|
||||
After running
|
||||
```shell
|
||||
CAPTION_MODEL_PATH=/PATH/TO/INTERNVL2_MODEL REWRITE_MODEL_PATH=/PATH/TO/REWRITE_MODEL sh scripts/stage_3_video_recaptioning.sh
|
||||
VILA_MODEL_PATH=/PATH/TO/VILA_MODEL REWRITE_MODEL_PATH=/PATH/TO/REWRITE_MODEL sh scripts/stage_3_video_recaptioning.sh
|
||||
```
|
||||
the final train file is obtained in `easyanimate/video_caption/datasets/panda_70m/videos_clips/meta_train_info.json`.
|
||||
the final train file is obtained in `cogvideox/video_caption/datasets/panda_70m/videos_clips/meta_train_info.json`.
|
||||
|
||||
|
||||
### Beautiful Prompt (For EasyAnimate Inference)
|
||||
Beautiful Prompt aims to rewrite and beautify the user-uploaded prompt via LLMs, mapping it to the style of EasyAnimate's training captions,
|
||||
### Beautiful Prompt (For CogVideoX-Fun Inference)
|
||||
Beautiful Prompt aims to rewrite and beautify the user-uploaded prompt via LLMs, mapping it to the style of CogVideoX-Fun's training captions,
|
||||
making it more suitable as the inference prompt and thus improving the quality of the generated videos.
|
||||
We support batched inference with local LLMs or OpenAI compatible server based on [vLLM](https://github.com/vllm-project/vllm) for beautiful prompt.
|
||||
|
||||
#### Batched Inference
|
||||
1. Prepare original prompts in a jsonl file `easyanimate/video_caption/datasets/original_prompt.jsonl` with the following format:
|
||||
1. Prepare original prompts in a jsonl file `cogvideox/video_caption/datasets/original_prompt.jsonl` with the following format:
|
||||
```json
|
||||
{"prompt": "A stylish woman in a black leather jacket, red dress, and boots walks confidently down a damp Tokyo street."}
|
||||
{"prompt": "An underwater world with realistic fish and other creatures of the sea."}
|
||||
@@ -140,13 +139,10 @@ We support batched inference with local LLMs or OpenAI compatible server based o
|
||||
python caption_rewrite.py \
|
||||
--video_metadata_path datasets/original_prompt.jsonl \
|
||||
--caption_column "prompt" \
|
||||
--beautiful_prompt_column "beautiful_prompt" \
|
||||
--batch_size 1 \
|
||||
--model_name /path/to/your_llm \
|
||||
--prompt prompt/beautiful_prompt.txt \
|
||||
--prefix '"detailed description": ' \
|
||||
--answer_template "your detailed description here" \
|
||||
--max_retry_count 10 \
|
||||
--saved_path datasets/beautiful_prompt.jsonl \
|
||||
--saved_freq 1
|
||||
```
|
||||
@@ -1,7 +1,7 @@
|
||||
# 数据预处理
|
||||
[English](./README.md) | 简体中文
|
||||
|
||||
该文件夹包含 EasyAnimate 使用的数据集预处理(即视频切分、过滤和生成描述)和提示词美化的代码。整个过程支持分布式并行处理,能够处理大规模数据集。
|
||||
该文件夹包含 CogVideoX-Fun 使用的数据集预处理(即视频切分、过滤和生成描述)和提示词美化的代码。整个过程支持分布式并行处理,能够处理大规模数据集。
|
||||
|
||||
此外,我们和 [Data-Juicer](https://github.com/modelscope/data-juicer/blob/main/docs/DJ_SORA.md) 合作,能让你在 [Aliyun PAI-DLC](https://help.aliyun.com/zh/pai/user-guide/video-preprocessing/) 轻松进行视频数据的处理。
|
||||
|
||||
@@ -24,18 +24,20 @@
|
||||
### 安装
|
||||
推荐使用阿里云 DSW 和 Docker 来安装环境,请参考 [快速开始](../../README_zh-CN.md#1-云使用-aliyundswdocker). 你也可以参考 [Dockerfile](../../Dockerfile.ds) 中的镜像构建流程在本地安装对应的 conda 环境和其余依赖。
|
||||
|
||||
为了提高推理速度和节省推理的显存,生成视频描述依赖于 [llm-awq](https://github.com/mit-han-lab/llm-awq)。因此,需要 RTX 3060 或者 A2 及以上的显卡 (CUDA Compute Capability >= 8.0)。
|
||||
|
||||
```shell
|
||||
# pull image
|
||||
docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:easyanimate
|
||||
docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# enter image
|
||||
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:easyanimate
|
||||
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# clone code
|
||||
git clone https://github.com/aigc-apps/EasyAnimate.git
|
||||
git clone https://github.com/aigc-apps/CogVideoX-Fun.git
|
||||
|
||||
# enter video_caption
|
||||
cd EasyAnimate/easyanimate/video_caption
|
||||
cd CogVideoX-Fun/cogvideox/video_caption
|
||||
```
|
||||
|
||||
### 数据集预处理
|
||||
@@ -51,7 +53,7 @@ cd EasyAnimate/easyanimate/video_caption
|
||||
```
|
||||
|
||||
#### 视频切分
|
||||
EasyAnimate 使用 [PySceneDetect](https://github.com/Breakthrough/PySceneDetect) 来识别视频中的场景变化
|
||||
CogVideoX-Fun 使用 [PySceneDetect](https://github.com/Breakthrough/PySceneDetect) 来识别视频中的场景变化
|
||||
并根据某些阈值通过 FFmpeg 执行视频分割,以确保视频片段的一致性。
|
||||
短于 3 秒的视频片段将被丢弃,长于 10 秒的视频片段将被递归切分。
|
||||
|
||||
@@ -59,12 +61,11 @@ EasyAnimate 使用 [PySceneDetect](https://github.com/Breakthrough/PySceneDetect
|
||||
```shell
|
||||
sh scripts/stage_1_video_splitting.sh
|
||||
```
|
||||
后,切分后的视频位于 `easyanimate/video_caption/datasets/panda_70m/videos_clips/data/`。
|
||||
后,切分后的视频位于 `cogvideox/video_caption/datasets/panda_70m/videos_clips/data/`。
|
||||
|
||||
#### 视频过滤
|
||||
基于上一步获得的视频,EasyAnimate 提供了一个简单而有效的流程来过滤出高质量的视频。总体流程如下:
|
||||
基于上一步获得的视频,CogVideoX-Fun 提供了一个简单而有效的流程来过滤出高质量的视频。总体流程如下:
|
||||
|
||||
- 场景跳变过滤:通过 [CLIP](https://github.com/openai/CLIP) 或者 [DINOv2](https://github.com/facebookresearch/dinov2) 来计算关键帧和首尾帧的语义相似度,从而过滤掉由于 PySceneDetect 缺失或多余分割引入的场景跳变的视频。
|
||||
- 美学过滤:通过 [aesthetic-predictor-v2-5](https://github.com/discus0434/aesthetic-predictor-v2-5) 计算均匀采样的 4 帧视频的平均美学分数,从而筛选出内容不佳(模糊、昏暗等)的视频。
|
||||
- 文本过滤:使用 [EasyOCR](https://github.com/JaidedAI/EasyOCR) 计算中间帧的文本区域比例,过滤掉含有大面积文本的视频。
|
||||
- 运动过滤:计算帧间光流差,过滤掉移动太慢或太快的视频。
|
||||
@@ -73,19 +74,19 @@ sh scripts/stage_1_video_splitting.sh
|
||||
```shell
|
||||
sh scripts/stage_2_video_filtering.sh
|
||||
```
|
||||
后,视频的美学得分、文本得分和运动得分对应的元文件保存在 `easyanimate/video_caption/datasets/panda_70m/videos_clips/`。
|
||||
后,视频的美学得分、文本得分和运动得分对应的元文件保存在 `cogvideox/video_caption/datasets/panda_70m/videos_clips/`。
|
||||
|
||||
> [!NOTE]
|
||||
> 美学得分的计算依赖于 [google/siglip-so400m-patch14-384 model](https://huggingface.co/google/siglip-so400m-patch14-384).
|
||||
请执行 `HF_ENDPOINT=https://hf-mirror.com sh scripts/stage_2_video_filtering.sh` 如果你无法访问 huggingface.com.
|
||||
|
||||
#### 视频描述
|
||||
在获得上述高质量的过滤视频后,EasyAnimate 利用 [InternVL2](https://internvl.readthedocs.io/en/latest/internvl2.0/introduction.html) 来生成视频描述。随后,使用 LLMs 对生成的视频描述进行重写,以更好地满足视频生成任务的要求。最后,使用自研的 [VideoCLIP-XL](https://arxiv.org/abs/2410.00741) 模型来过滤掉描述和视频内容不一致的数据,从而得到最终的训练数据集。
|
||||
在获得上述高质量的过滤视频后,CogVideoX-Fun 利用 [VILA1.5](https://github.com/NVlabs/VILA) 来生成视频描述。随后,使用 LLMs 对生成的视频描述进行重写,以更好地满足视频生成任务的要求。最后,使用自研的 VideoCLIPXL 模型来过滤掉描述和视频内容不一致的数据,从而得到最终的训练数据集。
|
||||
|
||||
请根据机器的显存从 [InternVL2](https://huggingface.co/collections/OpenGVLab/internvl-20-667d3961ab5eb12c7ed1463e) 下载合适大小的模型。对于 A100 40G,你可以执行下面的命令来下载 [InternVL2-40B-AWQ](https://huggingface.co/OpenGVLab/InternVL2-40B-AWQ)
|
||||
请根据机器的显存从 [VILA1.5](https://huggingface.co/collections/Efficient-Large-Model/vila-on-pre-training-for-visual-language-models-65d8022a3a52cd9bcd62698e) 下载合适大小的模型。对于 A100 40G,你可以执行下面的命令来下载 [VILA1.5-40b-AWQ](https://huggingface.co/Efficient-Large-Model/VILA1.5-40b-AWQ)
|
||||
```shell
|
||||
# Add HF_ENDPOINT=https://hf-mirror.com before the command if you cannot access to huggingface.com
|
||||
huggingface-cli download OpenGVLab/InternVL2-40B-AWQ --local-dir-use-symlinks False --local-dir /PATH/TO/INTERNVL2_MODEL
|
||||
huggingface-cli download Efficient-Large-Model/VILA1.5-40b-AWQ --local-dir-use-symlinks False --local-dir /PATH/TO/VILA_MODEL
|
||||
```
|
||||
|
||||
你可以选择性地准备 LLMs 来改写上述视频描述的结果。例如,你执行下面的命令来下载 [Meta-Llama-3-8B-Instruct](https://huggingface.co/NousResearch/Meta-Llama-3-8B-Instruct)
|
||||
@@ -97,18 +98,18 @@ huggingface-cli download NousResearch/Meta-Llama-3-8B-Instruct --local-dir-use-s
|
||||
视频描述的完整流程在 [stage_3_video_recaptioning.sh](./scripts/stage_3_video_recaptioning.sh).
|
||||
执行
|
||||
```shell
|
||||
CAPTION_MODEL_PATH=/PATH/TO/INTERNVL2_MODEL REWRITE_MODEL_PATH=/PATH/TO/REWRITE_MODEL sh scripts/stage_3_video_recaptioning.sh
|
||||
VILA_MODEL_PATH=/PATH/TO/VILA_MODEL REWRITE_MODEL_PATH=/PATH/TO/REWRITE_MODEL sh scripts/stage_3_video_recaptioning.sh
|
||||
```
|
||||
后,最后的训练文件会保存在 `easyanimate/video_caption/datasets/panda_70m/videos_clips/meta_train_info.json`。
|
||||
后,最后的训练文件会保存在 `cogvideox/video_caption/datasets/panda_70m/videos_clips/meta_train_info.json`。
|
||||
|
||||
### 提示词美化
|
||||
提示词美化旨在通过 LLMs 重写和美化用户上传的提示,将其映射为 EasyAnimate 训练所使用的视频描述风格、
|
||||
提示词美化旨在通过 LLMs 重写和美化用户上传的提示,将其映射为 CogVideoX-Fun 训练所使用的视频描述风格、
|
||||
使其更适合用作推理提示词,从而提高生成视频的质量。
|
||||
|
||||
基于 [vLLM](https://github.com/vllm-project/vllm),我们支持使用本地 LLM 进行批量推理或请求 OpenAI 服务器的方式,以进行提示词美化。
|
||||
|
||||
#### 批量推理
|
||||
1. 将原始的提示词以下面的格式准备在文件 `easyanimate/video_caption/datasets/original_prompt.jsonl` 中:
|
||||
1. 将原始的提示词以下面的格式准备在文件 `cogvideox/video_caption/datasets/original_prompt.jsonl` 中:
|
||||
```json
|
||||
{"prompt": "A stylish woman in a black leather jacket, red dress, and boots walks confidently down a damp Tokyo street."}
|
||||
{"prompt": "An underwater world with realistic fish and other creatures of the sea."}
|
||||
@@ -125,13 +126,10 @@ CAPTION_MODEL_PATH=/PATH/TO/INTERNVL2_MODEL REWRITE_MODEL_PATH=/PATH/TO/REWRITE_
|
||||
python caption_rewrite.py \
|
||||
--video_metadata_path datasets/original_prompt.jsonl \
|
||||
--caption_column "prompt" \
|
||||
--beautiful_prompt_column "beautiful_prompt" \
|
||||
--batch_size 1 \
|
||||
--model_name /path/to/your_llm \
|
||||
--prompt prompt/beautiful_prompt.txt \
|
||||
--prefix '"detailed description": ' \
|
||||
--answer_template "your detailed description here" \
|
||||
--max_retry_count 10 \
|
||||
--saved_path datasets/beautiful_prompt.jsonl \
|
||||
--saved_freq 1
|
||||
```
|
||||
@@ -1,5 +1,5 @@
|
||||
"""
|
||||
This script (optional) can rewrite and beautify the user-uploaded prompt via LLMs, mapping it to the style of EasyAnimate's training captions,
|
||||
This script (optional) can rewrite and beautify the user-uploaded prompt via LLMs, mapping it to the style of cogvideox's training captions,
|
||||
making it more suitable as the inference prompt and thus improving the quality of the generated videos.
|
||||
|
||||
Usage:
|
||||
@@ -32,7 +32,7 @@ import os
|
||||
|
||||
from openai import OpenAI
|
||||
|
||||
from easyanimate.video_caption.caption_rewrite import extract_output
|
||||
from cogvideox.video_caption.caption_rewrite import extract_output
|
||||
|
||||
|
||||
def parse_args():
|
||||
@@ -42,7 +42,7 @@ def parse_args():
|
||||
parser.add_argument(
|
||||
"--template",
|
||||
type=str,
|
||||
default="easyanimate/video_caption/prompt/beautiful_prompt.txt",
|
||||
default="cogvideox/video_caption/prompt/beautiful_prompt.txt",
|
||||
help="A string or a txt file contains the template for beautiful prompt."
|
||||
)
|
||||
parser.add_argument(
|
||||
@@ -1,14 +1,13 @@
|
||||
import argparse
|
||||
import os
|
||||
import re
|
||||
from copy import deepcopy
|
||||
import os
|
||||
from tqdm import tqdm
|
||||
|
||||
import pandas as pd
|
||||
import torch
|
||||
from natsort import index_natsorted
|
||||
from tqdm import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from vllm import LLM, SamplingParams
|
||||
from transformers import AutoTokenizer
|
||||
|
||||
from utils.logger import logger
|
||||
|
||||
@@ -33,26 +32,6 @@ def extract_output(s, prefix='"rewritten description": '):
|
||||
logger.warning(f"{output} does not start with {prefix}. Return None.")
|
||||
return None
|
||||
|
||||
"""The file unifies the following two tasks:
|
||||
1. Caption Rewrite: rewrite the video recaption results by LLMs.
|
||||
2. Beautiful Prompt: rewrite and beautify the user-uploaded prompt via LLMs.
|
||||
|
||||
For the caption rewrite task, the input video_metadata_path should have the following format:
|
||||
```jsonl
|
||||
{"video_path_column": "1.mp4", "caption_column": "a man is running in the street."}
|
||||
...
|
||||
{"video_path_column": "100.mp4", "caption_column": "a dog is chasing a cat."}
|
||||
```
|
||||
The video_path_column in the argparse must be specified.
|
||||
|
||||
For the beautiful prompt task, the input video_metadata_path should have the following format:
|
||||
```jsonl
|
||||
{"caption_column": "a man is running in the street."}
|
||||
...
|
||||
{"caption_column": "a dog is chasing a cat."}
|
||||
```
|
||||
The beautiful_prompt_column in the argparse must be specified for the saving purpose.
|
||||
"""
|
||||
|
||||
def parse_args():
|
||||
parser = argparse.ArgumentParser(description="Rewrite the video caption by LLMs.")
|
||||
@@ -63,10 +42,7 @@ def parse_args():
|
||||
"--video_path_column",
|
||||
type=str,
|
||||
default=None,
|
||||
help=(
|
||||
"The column contains the video path (an absolute path or a relative path w.r.t the video_folder)."
|
||||
"It is conflicted with the beautiful_prompt_column."
|
||||
),
|
||||
help="The column contains the video path (an absolute path or a relative path w.r.t the video_folder).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--caption_column",
|
||||
@@ -74,12 +50,6 @@ def parse_args():
|
||||
default="caption",
|
||||
help="The column contains the video caption.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--beautiful_prompt_column",
|
||||
type=str,
|
||||
default=None,
|
||||
help="The column name for the beautiful prompt column. It is conflicted with the video_path_column.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--batch_size",
|
||||
type=int,
|
||||
@@ -104,18 +74,6 @@ def parse_args():
|
||||
required=True,
|
||||
help="The prefix to extract the output from LLMs.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--answer_template",
|
||||
type=str,
|
||||
default="",
|
||||
help="The anwer template in the prompt. If specified, rewritten results same as the answer template will be removed.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--max_retry_count",
|
||||
type=int,
|
||||
default=1,
|
||||
help="The maximum retry count to ensure outputs with the valid format from LLMs.",
|
||||
)
|
||||
parser.add_argument("--saved_path", type=str, required=True, help="The save path to the output results (csv/jsonl).")
|
||||
parser.add_argument("--saved_freq", type=int, default=1, help="The frequency to save the output results.")
|
||||
|
||||
@@ -138,34 +96,20 @@ def main():
|
||||
saved_suffix = os.path.splitext(args.saved_path)[1]
|
||||
if saved_suffix not in set([".csv", ".jsonl", ".json"]):
|
||||
raise ValueError(f"The saved_path must end with .csv, .jsonl or .json.")
|
||||
|
||||
if args.video_path_column is None and args.beautiful_prompt_column is None:
|
||||
raise ValueError("Either video_path_column or beautiful_prompt_column should be specified in the arguments.")
|
||||
if args.video_path_column is not None and args.beautiful_prompt_column is not None:
|
||||
raise ValueError(
|
||||
"Both video_path_column and beautiful_prompt_column can not be specified in the arguments at the same time."
|
||||
)
|
||||
|
||||
if os.path.exists(args.saved_path):
|
||||
if os.path.exists(args.saved_path) and args.video_path_column is not None:
|
||||
if args.saved_path.endswith(".csv"):
|
||||
saved_metadata_df = pd.read_csv(args.saved_path)
|
||||
elif args.saved_path.endswith(".jsonl"):
|
||||
saved_metadata_df = pd.read_json(args.saved_path, lines=True)
|
||||
|
||||
if args.video_path_column is not None:
|
||||
# Filter out the unprocessed video-caption pairs by setting the indicator=True.
|
||||
merged_df = video_metadata_df.merge(saved_metadata_df, on=args.video_path_column, how="outer", indicator=True)
|
||||
video_metadata_df = merged_df[merged_df["_merge"] == "left_only"]
|
||||
# Sorting to guarantee the same result for each process.
|
||||
video_metadata_df = video_metadata_df.iloc[index_natsorted(video_metadata_df[args.video_path_column])]
|
||||
video_metadata_df = video_metadata_df.reset_index(drop=True)
|
||||
if args.beautiful_prompt_column is not None:
|
||||
# Filter out the unprocessed caption-beautifil_prompt pairs by setting the indicator=True.
|
||||
merged_df = video_metadata_df.merge(saved_metadata_df, on=args.caption_column, how="outer", indicator=True)
|
||||
video_metadata_df = merged_df[merged_df["_merge"] == "left_only"]
|
||||
# Sorting to guarantee the same result for each process.
|
||||
video_metadata_df = video_metadata_df.iloc[index_natsorted(video_metadata_df[args.caption_column])]
|
||||
video_metadata_df = video_metadata_df.reset_index(drop=True)
|
||||
# Filter out the unprocessed video-caption pairs by setting the indicator=True.
|
||||
merged_df = video_metadata_df.merge(saved_metadata_df, on=args.video_path_column, how="outer", indicator=True)
|
||||
video_metadata_df = merged_df[merged_df["_merge"] == "left_only"]
|
||||
# Sorting to guarantee the same result for each process.
|
||||
video_metadata_df = video_metadata_df.iloc[index_natsorted(video_metadata_df[args.video_path_column])].reset_index(
|
||||
drop=True
|
||||
)
|
||||
logger.info(
|
||||
f"Resume from {args.saved_path}: {len(saved_metadata_df)} processed and {len(video_metadata_df)} to be processed."
|
||||
)
|
||||
@@ -175,9 +119,6 @@ def main():
|
||||
args.prompt = "".join(f.readlines())
|
||||
logger.info(f"Prompt: {args.prompt}")
|
||||
|
||||
if args.max_retry_count < 1:
|
||||
raise ValueError(f"The max_retry_count {args.max_retry_count} must be greater than 0.")
|
||||
|
||||
if args.video_path_column is not None:
|
||||
video_path_list = video_metadata_df[args.video_path_column].tolist()
|
||||
if args.caption_column in video_metadata_df.columns:
|
||||
@@ -204,10 +145,9 @@ def main():
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.model_name)
|
||||
sampling_params = SamplingParams(temperature=0.7, top_p=1, max_tokens=1024)
|
||||
|
||||
result_dict = {args.caption_column: []}
|
||||
if args.video_path_column is not None:
|
||||
result_dict = {args.video_path_column: [], args.caption_column: []}
|
||||
if args.beautiful_prompt_column is not None:
|
||||
result_dict = {args.caption_column: [], args.beautiful_prompt_column: []}
|
||||
|
||||
for i in tqdm(range(0, len(sampled_frame_caption_list), args.batch_size)):
|
||||
if args.video_path_column is not None:
|
||||
@@ -222,77 +162,63 @@ def main():
|
||||
]
|
||||
text = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
|
||||
batch_prompt.append(text)
|
||||
|
||||
cur_retry_count = 0
|
||||
while cur_retry_count < args.max_retry_count:
|
||||
if len(batch_prompt) == 0:
|
||||
break
|
||||
|
||||
batch_result = []
|
||||
batch_output = llm.generate(batch_prompt, sampling_params)
|
||||
batch_output = [output.outputs[0].text.rstrip() for output in batch_output]
|
||||
if args.prefix is not None:
|
||||
batch_output = [extract_output(output, args.prefix) for output in batch_output]
|
||||
batch_output = llm.generate(batch_prompt, sampling_params)
|
||||
batch_output = [output.outputs[0].text.rstrip() for output in batch_output]
|
||||
batch_output = [extract_output(output, prefix=args.prefix) for output in batch_output]
|
||||
|
||||
if args.video_path_column is not None:
|
||||
retry_batch_video_path, retry_batch_prompt = [], []
|
||||
for (video_path, prompt, output) in zip(batch_video_path, batch_prompt, batch_output):
|
||||
# Filter out data that does not meet the output format to retry.
|
||||
if output is not None and output != args.answer_template:
|
||||
batch_result.append((video_path, output))
|
||||
else:
|
||||
retry_batch_video_path.append(video_path)
|
||||
retry_batch_prompt.append(prompt)
|
||||
if len(batch_result) != 0:
|
||||
batch_video_path, batch_output = zip(*batch_result)
|
||||
result_dict[args.video_path_column].extend(deepcopy(batch_video_path))
|
||||
result_dict[args.caption_column].extend(deepcopy(batch_output))
|
||||
|
||||
batch_video_path, batch_prompt = retry_batch_video_path, retry_batch_prompt
|
||||
if args.beautiful_prompt_column is not None:
|
||||
retry_batch_caption, retry_batch_prompt = [], []
|
||||
for (caption, prompt, output) in zip(batch_caption, batch_prompt, batch_output):
|
||||
# Filter out data that does not meet the output format to retry.
|
||||
if output is not None and output != args.answer_template:
|
||||
batch_result.append((caption, output))
|
||||
else:
|
||||
retry_batch_caption.append(caption)
|
||||
retry_batch_prompt.append(prompt)
|
||||
if len(batch_result) != 0:
|
||||
batch_caption, batch_output = zip(*batch_result)
|
||||
result_dict[args.caption_column].extend(deepcopy(batch_caption))
|
||||
result_dict[args.beautiful_prompt_column].extend(deepcopy(batch_output))
|
||||
|
||||
batch_caption, batch_prompt = retry_batch_caption, retry_batch_prompt
|
||||
|
||||
cur_retry_count += 1
|
||||
logger.info(
|
||||
f"Current retry count/Maximum retry count: {cur_retry_count}/{args.max_retry_count}.: "
|
||||
f"Retrying {len(batch_prompt)} prompts with invalid output format."
|
||||
)
|
||||
# Filter out data that does not meet the output format.
|
||||
batch_result = []
|
||||
if args.video_path_column is not None:
|
||||
for video_path, output in zip(batch_video_path, batch_output):
|
||||
if output is not None:
|
||||
batch_result.append((video_path, output))
|
||||
batch_video_path, batch_output = zip(*batch_result)
|
||||
|
||||
result_dict[args.video_path_column].extend(batch_video_path)
|
||||
else:
|
||||
for output in batch_output:
|
||||
if output is not None:
|
||||
batch_result.append(output)
|
||||
|
||||
result_dict[args.caption_column].extend(batch_result)
|
||||
|
||||
# Save the metadata every args.saved_freq.
|
||||
if (i // args.batch_size) % args.saved_freq == 0 or (i + 1) * args.batch_size >= len(sampled_frame_caption_list):
|
||||
if i != 0 and ((i // args.batch_size) % args.saved_freq) == 0:
|
||||
if len(result_dict[args.caption_column]) > 0:
|
||||
result_df = pd.DataFrame(result_dict)
|
||||
# Append is not supported (oss).
|
||||
if args.saved_path.endswith(".csv"):
|
||||
if os.path.exists(args.saved_path):
|
||||
saved_df = pd.read_csv(args.saved_path)
|
||||
result_df = pd.concat([saved_df, result_df], ignore_index=True)
|
||||
result_df.to_csv(args.saved_path, index=False)
|
||||
header = True if not os.path.exists(args.saved_path) else False
|
||||
result_df.to_csv(args.saved_path, header=header, index=False, mode="a")
|
||||
elif args.saved_path.endswith(".jsonl"):
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, mode="a", force_ascii=False)
|
||||
elif args.saved_path.endswith(".json"):
|
||||
# Append is not supported.
|
||||
if os.path.exists(args.saved_path):
|
||||
saved_df = pd.read_json(args.saved_path, orient="records", lines=True)
|
||||
saved_df = pd.read_json(args.saved_path, orient="records")
|
||||
result_df = pd.concat([saved_df, result_df], ignore_index=True)
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, force_ascii=False)
|
||||
result_df.to_json(args.saved_path, orient="records", indent=4, force_ascii=False)
|
||||
logger.info(f"Save result to {args.saved_path}.")
|
||||
|
||||
result_dict = {args.caption_column: []}
|
||||
if args.video_path_column is not None:
|
||||
result_dict = {args.video_path_column: [], args.caption_column: []}
|
||||
if args.beautiful_prompt_column is not None:
|
||||
result_dict = {args.caption_column: [], args.beautiful_prompt_column: []}
|
||||
|
||||
if len(result_dict[args.caption_column]) > 0:
|
||||
result_df = pd.DataFrame(result_dict)
|
||||
if args.saved_path.endswith(".csv"):
|
||||
header = True if not os.path.exists(args.saved_path) else False
|
||||
result_df.to_csv(args.saved_path, header=header, index=False, mode="a")
|
||||
elif args.saved_path.endswith(".jsonl"):
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, mode="a")
|
||||
elif args.saved_path.endswith(".json"):
|
||||
# Append is not supported.
|
||||
if os.path.exists(args.saved_path):
|
||||
saved_df = pd.read_json(args.saved_path, orient="records")
|
||||
result_df = pd.concat([saved_df, result_df], ignore_index=True)
|
||||
result_df.to_json(args.saved_path, orient="records", indent=4, force_ascii=False)
|
||||
logger.info(f"Save the final result to {args.saved_path}.")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -1,7 +1,9 @@
|
||||
import ast
|
||||
import argparse
|
||||
import gc
|
||||
import os
|
||||
from contextlib import contextmanager
|
||||
from pathlib import Path
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
@@ -10,8 +12,8 @@ from joblib import Parallel, delayed
|
||||
from natsort import natsorted
|
||||
from tqdm import tqdm
|
||||
|
||||
from utils.filter import filter
|
||||
from utils.logger import logger
|
||||
from utils.filter import filter
|
||||
|
||||
|
||||
@contextmanager
|
||||
@@ -74,11 +76,11 @@ def compute_motion_score(video_path):
|
||||
video_motion_scores.append(frame_motion_score)
|
||||
prev_frame = gray_frame
|
||||
|
||||
motion_score_result = {
|
||||
"video_path": video_path,
|
||||
video_meta_info = {
|
||||
"video_path": Path(video_path).name,
|
||||
"motion_score": round(float(np.mean(video_motion_scores)), 5),
|
||||
}
|
||||
return motion_score_result
|
||||
return video_meta_info
|
||||
|
||||
except Exception as e:
|
||||
print(f"Compute motion score for video {video_path} with error: {e}.")
|
||||
@@ -97,35 +99,27 @@ def parse_args():
|
||||
help="The column contains the video path (an absolute path or a relative path w.r.t the video_folder).",
|
||||
)
|
||||
parser.add_argument("--saved_path", type=str, required=True, help="The save path to the output results (csv/jsonl).")
|
||||
parser.add_argument("--saved_freq", type=int, default=1, help="The frequency to save the output results.")
|
||||
parser.add_argument("--saved_freq", type=int, default=100, help="The frequency to save the output results.")
|
||||
parser.add_argument("--n_jobs", type=int, default=1, help="The number of concurrent processes.")
|
||||
|
||||
parser.add_argument("--basic_metadata_path", type=str, default=None, help="The path to the basic metadata (csv/jsonl).")
|
||||
parser.add_argument(
|
||||
"--basic_metadata_path", type=str, default=None, help="The path to the basic metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_resolution", type=float, default=0, help="The resolution threshold.")
|
||||
parser.add_argument("--min_duration", type=float, default=-1, help="The minimum duration.")
|
||||
parser.add_argument("--max_duration", type=float, default=-1, help="The maximum duration.")
|
||||
parser.add_argument(
|
||||
"--aesthetic_score_metadata_path", type=str, default=None, help="The path to the video quality metadata (csv/jsonl)."
|
||||
"--asethetic_score_metadata_path", type=str, default=None, help="The path to the video quality metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_aesthetic_score", type=float, default=4.0, help="The aesthetic score threshold.")
|
||||
parser.add_argument("--min_asethetic_score", type=float, default=4.0, help="The asethetic score threshold.")
|
||||
parser.add_argument(
|
||||
"--aesthetic_score_siglip_metadata_path", type=str, default=None, help="The path to the video quality metadata (csv/jsonl)."
|
||||
"--asethetic_score_siglip_metadata_path", type=str, default=None, help="The path to the video quality metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_aesthetic_score_siglip", type=float, default=4.0, help="The aesthetic score (SigLIP) threshold.")
|
||||
parser.add_argument("--min_asethetic_score_siglip", type=float, default=4.0, help="The asethetic score (SigLIP) threshold.")
|
||||
parser.add_argument(
|
||||
"--text_score_metadata_path", type=str, default=None, help="The path to the video text score metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_text_score", type=float, default=0.02, help="The text threshold.")
|
||||
parser.add_argument(
|
||||
"--semantic_consistency_score_metadata_path",
|
||||
nargs="+",
|
||||
type=str,
|
||||
default=None,
|
||||
help="The path to the semantic consistency metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--min_semantic_consistency_score", type=float, default=0.80, help="The semantic consistency score threshold."
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
return args
|
||||
@@ -160,49 +154,33 @@ def main():
|
||||
min_resolution=args.min_resolution,
|
||||
min_duration=args.min_duration,
|
||||
max_duration=args.max_duration,
|
||||
aesthetic_score_metadata_path=args.aesthetic_score_metadata_path,
|
||||
min_aesthetic_score=args.min_aesthetic_score,
|
||||
aesthetic_score_siglip_metadata_path=args.aesthetic_score_siglip_metadata_path,
|
||||
min_aesthetic_score_siglip=args.min_aesthetic_score_siglip,
|
||||
asethetic_score_metadata_path=args.asethetic_score_metadata_path,
|
||||
min_asethetic_score=args.min_asethetic_score,
|
||||
asethetic_score_siglip_metadata_path=args.asethetic_score_siglip_metadata_path,
|
||||
min_asethetic_score_siglip=args.min_asethetic_score_siglip,
|
||||
text_score_metadata_path=args.text_score_metadata_path,
|
||||
min_text_score=args.min_text_score,
|
||||
semantic_consistency_score_metadata_path=args.semantic_consistency_score_metadata_path,
|
||||
min_semantic_consistency_score=args.min_semantic_consistency_score,
|
||||
video_path_column=args.video_path_column
|
||||
)
|
||||
video_path_list = [os.path.join(args.video_folder, video_path) for video_path in video_path_list]
|
||||
# Sorting to guarantee the same result for each process.
|
||||
video_path_list = natsorted(video_path_list)
|
||||
logger.info(f"{len(video_path_list)} videos are to be processed.")
|
||||
|
||||
for i in tqdm(range(0, len(video_path_list), args.saved_freq)):
|
||||
# Get motion score result for each video asynchronously.
|
||||
motion_score_result_list = Parallel(n_jobs=args.n_jobs)(
|
||||
result_list = Parallel(n_jobs=args.n_jobs)(
|
||||
delayed(compute_motion_score)(video_path) for video_path in tqdm(video_path_list[i: i + args.saved_freq])
|
||||
)
|
||||
result_list = []
|
||||
for motion_score_result in motion_score_result_list:
|
||||
if motion_score_result is not None:
|
||||
video_path = motion_score_result["video_path"]
|
||||
if args.video_folder != "":
|
||||
video_path = os.path.relpath(video_path, args.video_folder)
|
||||
result_list.append({args.video_path_column: video_path, "motion_score": motion_score_result["motion_score"]})
|
||||
result_list = [result for result in result_list if result is not None]
|
||||
if len(result_list) == 0:
|
||||
continue
|
||||
|
||||
result_df = pd.DataFrame(result_list)
|
||||
# Append is not supported (oss).
|
||||
if args.saved_path.endswith(".csv"):
|
||||
if os.path.exists(args.saved_path):
|
||||
saved_df = pd.read_csv(args.saved_path)
|
||||
result_df = pd.concat([saved_df, result_df], ignore_index=True)
|
||||
result_df.to_csv(args.saved_path, index=False)
|
||||
header = False if os.path.exists(args.saved_path) else True
|
||||
result_df.to_csv(args.saved_path, header=header, index=False, mode="a")
|
||||
elif args.saved_path.endswith(".jsonl"):
|
||||
if os.path.exists(args.saved_path):
|
||||
saved_df = pd.read_json(args.saved_path, orient="records", lines=True)
|
||||
result_df = pd.concat([saved_df, result_df], ignore_index=True)
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, force_ascii=False)
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, mode="a", force_ascii=False)
|
||||
logger.info(f"Save result to {args.saved_path}.")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -1,5 +1,6 @@
|
||||
import argparse
|
||||
import os
|
||||
from pathlib import Path
|
||||
|
||||
import easyocr
|
||||
import numpy as np
|
||||
@@ -10,9 +11,9 @@ from natsort import natsorted
|
||||
from tqdm import tqdm
|
||||
from torchvision.datasets.utils import download_url
|
||||
|
||||
from utils.filter import filter
|
||||
from utils.logger import logger
|
||||
from utils.video_utils import extract_frames
|
||||
from utils.filter import filter
|
||||
|
||||
|
||||
def init_ocr_reader(root: str = "~/.cache/easyocr", device: str = "gpu"):
|
||||
@@ -46,8 +47,8 @@ def triangle_area(p1, p2, p3):
|
||||
return tri_area
|
||||
|
||||
|
||||
def compute_text_score(video_path, ocr_reader, sample_method="mid", num_sampled_frames=1):
|
||||
_, images = extract_frames(video_path, sample_method=sample_method, num_sampled_frames=num_sampled_frames)
|
||||
def compute_text_score(video_path, ocr_reader):
|
||||
_, images = extract_frames(video_path, sample_method="mid")
|
||||
images = [np.array(image) for image in images]
|
||||
|
||||
frame_ocr_area_ratios = []
|
||||
@@ -77,9 +78,12 @@ def compute_text_score(video_path, ocr_reader, sample_method="mid", num_sampled_
|
||||
|
||||
frame_ocr_area_ratios.append(text_area / total_area)
|
||||
|
||||
text_score = round(np.mean(frame_ocr_area_ratios), 5)
|
||||
video_meta_info = {
|
||||
"video_path": Path(video_path).name,
|
||||
"text_score": round(np.mean(frame_ocr_area_ratios), 5),
|
||||
}
|
||||
|
||||
return text_score
|
||||
return video_meta_info
|
||||
|
||||
|
||||
def parse_args():
|
||||
@@ -94,47 +98,27 @@ def parse_args():
|
||||
default="video_path",
|
||||
help="The column contains the video path (an absolute path or a relative path w.r.t the video_folder).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--frame_sample_method",
|
||||
type=str,
|
||||
default="mid",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--num_sampled_frames",
|
||||
type=int,
|
||||
default=1,
|
||||
help="num_sampled_frames",
|
||||
)
|
||||
parser.add_argument("--saved_path", type=str, required=True, help="The save path to the output results (csv/jsonl).")
|
||||
parser.add_argument("--saved_freq", type=int, default=1, help="The frequency to save the output results.")
|
||||
parser.add_argument("--saved_freq", type=int, default=100, help="The frequency to save the output results.")
|
||||
|
||||
parser.add_argument("--basic_metadata_path", type=str, default=None, help="The path to the basic metadata (csv/jsonl).")
|
||||
parser.add_argument(
|
||||
"--basic_metadata_path", type=str, default=None, help="The path to the basic metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_resolution", type=float, default=0, help="The resolution threshold.")
|
||||
parser.add_argument("--min_duration", type=float, default=-1, help="The minimum duration.")
|
||||
parser.add_argument("--max_duration", type=float, default=-1, help="The maximum duration.")
|
||||
parser.add_argument(
|
||||
"--aesthetic_score_metadata_path", type=str, default=None, help="The path to the video quality metadata (csv/jsonl)."
|
||||
"--asethetic_score_metadata_path", type=str, default=None, help="The path to the video quality metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_aesthetic_score", type=float, default=4.0, help="The aesthetic score threshold.")
|
||||
parser.add_argument("--min_asethetic_score", type=float, default=4.0, help="The asethetic score threshold.")
|
||||
parser.add_argument(
|
||||
"--aesthetic_score_siglip_metadata_path", type=str, default=None, help="The path to the video quality metadata (csv/jsonl)."
|
||||
"--asethetic_score_siglip_metadata_path", type=str, default=None, help="The path to the video quality metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_aesthetic_score_siglip", type=float, default=4.0, help="The aesthetic score (SigLIP) threshold.")
|
||||
parser.add_argument("--min_asethetic_score_siglip", type=float, default=4.0, help="The asethetic score (SigLIP) threshold.")
|
||||
parser.add_argument(
|
||||
"--motion_score_metadata_path", type=str, default=None, help="The path to the video motion score metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_motion_score", type=float, default=2, help="The minimum motion threshold.")
|
||||
parser.add_argument("--max_motion_score", type=float, default=999999, help="The maximum motion threshold.")
|
||||
parser.add_argument(
|
||||
"--semantic_consistency_score_metadata_path",
|
||||
nargs="+",
|
||||
type=str,
|
||||
default=None,
|
||||
help="The path to the semantic consistency metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--min_semantic_consistency_score", type=float, default=0.80, help="The semantic consistency score threshold."
|
||||
)
|
||||
parser.add_argument("--min_motion_score", type=float, default=2, help="The motion threshold.")
|
||||
|
||||
args = parser.parse_args()
|
||||
return args
|
||||
@@ -169,16 +153,12 @@ def main():
|
||||
min_resolution=args.min_resolution,
|
||||
min_duration=args.min_duration,
|
||||
max_duration=args.max_duration,
|
||||
aesthetic_score_metadata_path=args.aesthetic_score_metadata_path,
|
||||
min_aesthetic_score=args.min_aesthetic_score,
|
||||
aesthetic_score_siglip_metadata_path=args.aesthetic_score_siglip_metadata_path,
|
||||
min_aesthetic_score_siglip=args.min_aesthetic_score_siglip,
|
||||
asethetic_score_metadata_path=args.asethetic_score_metadata_path,
|
||||
min_asethetic_score=args.min_asethetic_score,
|
||||
asethetic_score_siglip_metadata_path=args.asethetic_score_siglip_metadata_path,
|
||||
min_asethetic_score_siglip=args.min_asethetic_score_siglip,
|
||||
motion_score_metadata_path=args.motion_score_metadata_path,
|
||||
min_motion_score=args.min_motion_score,
|
||||
max_motion_score=args.max_motion_score,
|
||||
semantic_consistency_score_metadata_path=args.semantic_consistency_score_metadata_path,
|
||||
min_semantic_consistency_score=args.min_semantic_consistency_score,
|
||||
video_path_column=args.video_path_column
|
||||
)
|
||||
video_path_list = [os.path.join(args.video_folder, video_path) for video_path in video_path_list]
|
||||
# Sorting to guarantee the same result for each process.
|
||||
@@ -193,10 +173,7 @@ def main():
|
||||
|
||||
index = len(video_path_list) - len(video_path_list) % state.num_processes
|
||||
# Avoid the NCCL timeout in the final gather operation.
|
||||
logger.info(
|
||||
f"Drop the last {len(video_path_list) % state.num_processes} videos to "
|
||||
"ensure each process handles the same number of videos."
|
||||
)
|
||||
logger.info(f"Drop {len(video_path_list) % state.num_processes} videos to ensure each process handles the same number of videos.")
|
||||
video_path_list = video_path_list[:index]
|
||||
logger.info(f"{len(video_path_list)} videos are to be processed.")
|
||||
|
||||
@@ -204,39 +181,34 @@ def main():
|
||||
with state.split_between_processes(video_path_list) as splitted_video_path_list:
|
||||
for i, video_path in enumerate(tqdm(splitted_video_path_list)):
|
||||
try:
|
||||
text_score = compute_text_score(
|
||||
video_path,
|
||||
ocr_reader,
|
||||
sample_method=args.frame_sample_method,
|
||||
num_sampled_frames=args.num_sampled_frames,
|
||||
)
|
||||
video_meta_info = {}
|
||||
if args.video_folder == "":
|
||||
video_meta_info[args.video_path_column] = video_path
|
||||
else:
|
||||
video_meta_info[args.video_path_column] = os.path.relpath(video_path, args.video_folder)
|
||||
video_meta_info["text_score"] = text_score
|
||||
video_meta_info = compute_text_score(video_path, ocr_reader)
|
||||
result_list.append(video_meta_info)
|
||||
except Exception as e:
|
||||
logger.warning(f"Compute text score for video {video_path} with error: {e}.")
|
||||
if i % args.saved_freq == 0 or i == len(splitted_video_path_list) - 1:
|
||||
if i != 0 and i % args.saved_freq == 0:
|
||||
state.wait_for_everyone()
|
||||
gathered_result_list = gather_object(result_list)
|
||||
if state.is_main_process and len(gathered_result_list) != 0:
|
||||
result_df = pd.DataFrame(gathered_result_list)
|
||||
# Append is not supported (oss).
|
||||
if args.saved_path.endswith(".csv"):
|
||||
if os.path.exists(args.saved_path):
|
||||
saved_df = pd.read_csv(args.saved_path)
|
||||
result_df = pd.concat([saved_df, result_df], ignore_index=True)
|
||||
result_df.to_csv(args.saved_path, index=False)
|
||||
header = False if os.path.exists(args.saved_path) else True
|
||||
result_df.to_csv(args.saved_path, header=header, index=False, mode="a")
|
||||
elif args.saved_path.endswith(".jsonl"):
|
||||
if os.path.exists(args.saved_path):
|
||||
saved_df = pd.read_json(args.saved_path, orient="records", lines=True)
|
||||
result_df = pd.concat([saved_df, result_df], ignore_index=True)
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, force_ascii=False)
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, mode="a", force_ascii=False)
|
||||
logger.info(f"Save result to {args.saved_path}.")
|
||||
result_list = []
|
||||
|
||||
state.wait_for_everyone()
|
||||
gathered_result_list = gather_object(result_list)
|
||||
if state.is_main_process and len(gathered_result_list) != 0:
|
||||
result_df = pd.DataFrame(gathered_result_list)
|
||||
if args.saved_path.endswith(".csv"):
|
||||
header = False if os.path.exists(args.saved_path) else True
|
||||
result_df.to_csv(args.saved_path, header=header, index=False, mode="a")
|
||||
elif args.saved_path.endswith(".jsonl"):
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, mode="a", force_ascii=False)
|
||||
logger.info(f"Save the final result to {args.saved_path}.")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -10,7 +10,6 @@ from torch.utils.data import DataLoader
|
||||
|
||||
import utils.image_evaluator as image_evaluator
|
||||
import utils.video_evaluator as video_evaluator
|
||||
from utils.filter import filter
|
||||
from utils.logger import logger
|
||||
from utils.video_dataset import VideoDataset, collate_fn
|
||||
|
||||
@@ -27,43 +26,41 @@ def parse_args():
|
||||
help="The column contains the video path (an absolute path or a relative path w.r.t the video_folder).",
|
||||
)
|
||||
parser.add_argument("--video_folder", type=str, default="", help="The video folder.")
|
||||
parser.add_argument("--caption_column", type=str, default=None, help="The column contains the caption.")
|
||||
parser.add_argument(
|
||||
"--caption_column",
|
||||
type=str,
|
||||
default=None,
|
||||
help="The column contains the caption.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--frame_sample_method",
|
||||
type=str,
|
||||
choices=["mid", "uniform", "image"],
|
||||
default="uniform",
|
||||
)
|
||||
parser.add_argument("--num_sampled_frames", type=int, default=8, help="The number of sampled frames.")
|
||||
parser.add_argument(
|
||||
"--num_sampled_frames",
|
||||
type=int,
|
||||
default=8,
|
||||
help="num_sampled_frames",
|
||||
)
|
||||
parser.add_argument("--metrics", nargs="+", type=str, required=True, help="The evaluation metric(s) for generated images.")
|
||||
parser.add_argument("--batch_size", type=int, default=1, help="The batch size for the video dataset.")
|
||||
parser.add_argument("--num_workers", type=int, default=1, help="The number of workers for the video dataset.")
|
||||
parser.add_argument(
|
||||
"--batch_size",
|
||||
type=int,
|
||||
default=10,
|
||||
required=False,
|
||||
help="The batch size for the video dataset.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--num_workers",
|
||||
type=int,
|
||||
default=4,
|
||||
required=False,
|
||||
help="The number of workers for the video dataset.",
|
||||
)
|
||||
parser.add_argument("--saved_path", type=str, required=True, help="The save path to the output results (csv/jsonl).")
|
||||
parser.add_argument("--saved_freq", type=int, default=1, help="The frequency to save the output results.")
|
||||
|
||||
parser.add_argument("--basic_metadata_path", type=str, default=None, help="The path to the basic metadata (csv/jsonl).")
|
||||
parser.add_argument("--min_resolution", type=float, default=0, help="The resolution threshold.")
|
||||
parser.add_argument("--min_duration", type=float, default=-1, help="The minimum duration.")
|
||||
parser.add_argument("--max_duration", type=float, default=-1, help="The maximum duration.")
|
||||
parser.add_argument(
|
||||
"--text_score_metadata_path", type=str, default=None, help="The path to the video text score metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_text_score", type=float, default=0.02, help="The text threshold.")
|
||||
parser.add_argument(
|
||||
"--motion_score_metadata_path", type=str, default=None, help="The path to the video motion score metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_motion_score", type=float, default=2, help="The minimum motion threshold.")
|
||||
parser.add_argument("--max_motion_score", type=float, default=999999, help="The maximum motion threshold.")
|
||||
parser.add_argument(
|
||||
"--semantic_consistency_score_metadata_path",
|
||||
nargs="+",
|
||||
type=str,
|
||||
default=None,
|
||||
help="The path to the semantic consistency metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--min_semantic_consistency_score", type=float, default=0.80, help="The semantic consistency score threshold."
|
||||
)
|
||||
parser.add_argument("--saved_freq", type=int, default=1000, help="The frequency to save the output results.")
|
||||
|
||||
args = parser.parse_args()
|
||||
return args
|
||||
@@ -89,34 +86,16 @@ def main():
|
||||
saved_metadata_df = pd.read_json(args.saved_path, lines=True)
|
||||
|
||||
# Filter out the unprocessed video-caption pairs by setting the indicator=True.
|
||||
merged_df = video_metadata_df.merge(saved_metadata_df, on=args.video_path_column, how="outer", indicator=True)
|
||||
merged_df = video_metadata_df.merge(saved_metadata_df, on="video_path", how="outer", indicator=True)
|
||||
video_metadata_df = merged_df[merged_df["_merge"] == "left_only"]
|
||||
# Sorting to guarantee the same result for each process.
|
||||
video_metadata_df = video_metadata_df.iloc[index_natsorted(video_metadata_df[args.video_path_column])].reset_index(drop=True)
|
||||
video_metadata_df = video_metadata_df.iloc[index_natsorted(video_metadata_df["video_path"])].reset_index(drop=True)
|
||||
if args.caption_column is None:
|
||||
video_metadata_df = video_metadata_df[[args.video_path_column]]
|
||||
else:
|
||||
video_metadata_df = video_metadata_df[[args.video_path_column, args.caption_column + "_x"]]
|
||||
video_metadata_df.rename(columns={args.caption_column + "_x": args.caption_column}, inplace=True)
|
||||
logger.info(f"Resume from {args.saved_path}: {len(saved_metadata_df)} processed and {len(video_metadata_df)} to be processed.")
|
||||
|
||||
video_path_list = video_metadata_df[args.video_path_column].tolist()
|
||||
video_path_list = filter(
|
||||
video_path_list,
|
||||
basic_metadata_path=args.basic_metadata_path,
|
||||
min_resolution=args.min_resolution,
|
||||
min_duration=args.min_duration,
|
||||
max_duration=args.max_duration,
|
||||
text_score_metadata_path=args.text_score_metadata_path,
|
||||
min_text_score=args.min_text_score,
|
||||
motion_score_metadata_path=args.motion_score_metadata_path,
|
||||
min_motion_score=args.min_motion_score,
|
||||
max_motion_score=args.max_motion_score,
|
||||
semantic_consistency_score_metadata_path=args.semantic_consistency_score_metadata_path,
|
||||
min_semantic_consistency_score=args.min_semantic_consistency_score,
|
||||
video_path_column=args.video_path_column
|
||||
)
|
||||
video_metadata_df = video_metadata_df[video_metadata_df[args.video_path_column].isin(video_path_list)]
|
||||
|
||||
state = PartialState()
|
||||
metric_fns = []
|
||||
@@ -148,10 +127,7 @@ def main():
|
||||
|
||||
index = len(video_metadata_df) - len(video_metadata_df) % state.num_processes
|
||||
# Avoid the NCCL timeout in the final gather operation.
|
||||
logger.info(
|
||||
f"Drop the last {len(video_metadata_df) % state.num_processes} videos "
|
||||
"to ensure each process handles the same number of videos."
|
||||
)
|
||||
logger.info(f"Drop {len(video_metadata_df) % state.num_processes} videos to ensure each process handles the same number of videos.")
|
||||
video_metadata_df = video_metadata_df.iloc[:index]
|
||||
logger.info(f"{len(video_metadata_df)} videos are to be processed.")
|
||||
|
||||
@@ -160,7 +136,6 @@ def main():
|
||||
video_dataset = VideoDataset(
|
||||
dataset_inputs=splitted_video_metadata,
|
||||
video_folder=args.video_folder,
|
||||
video_path_column=args.video_path_column,
|
||||
text_column=args.caption_column,
|
||||
sample_method=args.frame_sample_method,
|
||||
num_sampled_frames=args.num_sampled_frames
|
||||
@@ -195,25 +170,32 @@ def main():
|
||||
result_dict[args.video_path_column].extend(saved_video_path_list)
|
||||
|
||||
# Save the metadata in the main process every saved_freq.
|
||||
if (idx % args.saved_freq) == 0 or idx == len(video_loader) - 1:
|
||||
if (idx != 0) and (idx % args.saved_freq == 0):
|
||||
state.wait_for_everyone()
|
||||
gathered_result_dict = {k: gather_object(v) for k, v in result_dict.items()}
|
||||
if state.is_main_process and len(gathered_result_dict[args.video_path_column]) != 0:
|
||||
result_df = pd.DataFrame(gathered_result_dict)
|
||||
# Append is not supported (oss).
|
||||
if args.saved_path.endswith(".csv"):
|
||||
if os.path.exists(args.saved_path):
|
||||
saved_df = pd.read_csv(args.saved_path)
|
||||
result_df = pd.concat([saved_df, result_df], ignore_index=True)
|
||||
result_df.to_csv(args.saved_path, index=False)
|
||||
header = False if os.path.exists(args.saved_path) else True
|
||||
result_df.to_csv(args.saved_path, header=header, index=False, mode="a")
|
||||
elif args.saved_path.endswith(".jsonl"):
|
||||
if os.path.exists(args.saved_path):
|
||||
saved_df = pd.read_json(args.saved_path, orient="records", lines=True)
|
||||
result_df = pd.concat([saved_df, result_df], ignore_index=True)
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, force_ascii=False)
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, mode="a", force_ascii=False)
|
||||
logger.info(f"Save result to {args.saved_path}.")
|
||||
for k in result_dict.keys():
|
||||
result_dict[k] = []
|
||||
|
||||
# Wait for all processes to finish and gather the final result.
|
||||
state.wait_for_everyone()
|
||||
gathered_result_dict = {k: gather_object(v) for k, v in result_dict.items()}
|
||||
# Save the metadata in the main process.
|
||||
if state.is_main_process and len(gathered_result_dict[args.video_path_column]) != 0:
|
||||
result_df = pd.DataFrame(gathered_result_dict)
|
||||
if args.saved_path.endswith(".csv"):
|
||||
header = False if os.path.exists(args.saved_path) else True
|
||||
result_df.to_csv(args.saved_path, header=header, index=False, mode="a")
|
||||
elif args.saved_path.endswith(".jsonl"):
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, mode="a", force_ascii=False)
|
||||
logger.info(f"Save the final result to {args.saved_path}.")
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -1,13 +1,14 @@
|
||||
import argparse
|
||||
import os
|
||||
from copy import deepcopy
|
||||
from multiprocessing import Pool
|
||||
from pathlib import Path
|
||||
from multiprocessing import Pool
|
||||
|
||||
import pandas as pd
|
||||
from scenedetect import SceneManager, open_video
|
||||
from scenedetect import open_video, SceneManager
|
||||
from scenedetect.detectors import ContentDetector
|
||||
from tqdm import tqdm
|
||||
|
||||
from utils.logger import logger
|
||||
|
||||
|
||||
@@ -15,14 +16,14 @@ def cutscene_detection_star(args):
|
||||
return cutscene_detection(*args)
|
||||
|
||||
|
||||
def cutscene_detection(video_path, video_folder, saved_path, cutscene_threshold=27, min_scene_len=15):
|
||||
def cutscene_detection(video_path, saved_path, cutscene_threshold=27, min_scene_len=15):
|
||||
try:
|
||||
if os.path.exists(saved_path):
|
||||
logger.info(f"{video_path} has been processed.")
|
||||
return
|
||||
# Use PyAV as the backend to avoid (to some exent) containing the last frame of the previous scene.
|
||||
# https://github.com/Breakthrough/PySceneDetect/issues/279#issuecomment-2152596761.
|
||||
video = open_video(os.path.join(video_folder, video_path), backend="pyav")
|
||||
video = open_video(video_path, backend="pyav")
|
||||
frame_rate, frame_size = video.frame_rate, video.frame_size
|
||||
duration = deepcopy(video.duration)
|
||||
|
||||
@@ -50,14 +51,12 @@ def cutscene_detection(video_path, video_folder, saved_path, cutscene_threshold=
|
||||
|
||||
timecode_list = [(frame_timecode_tuple[0].get_timecode(), frame_timecode_tuple[1].get_timecode()) for frame_timecode_tuple in output_scene_list]
|
||||
meta_scene = [{
|
||||
"video_path": video_path,
|
||||
"video_path": Path(video_path).name,
|
||||
"timecode_list": timecode_list,
|
||||
"fram_rate": frame_rate,
|
||||
"frame_size": frame_size,
|
||||
"duration": str(duration) # __repr__
|
||||
}]
|
||||
if not os.path.exists(Path(saved_path).parent):
|
||||
os.makedirs(Path(saved_path).parent, exist_ok=True)
|
||||
pd.DataFrame(meta_scene).to_json(saved_path, orient="records", lines=True)
|
||||
except Exception as e:
|
||||
logger.warning(f"Cutscene detection with {video_path} failed. Error is: {e}.")
|
||||
@@ -76,18 +75,20 @@ if __name__ == "__main__":
|
||||
)
|
||||
parser.add_argument("--video_folder", type=str, default="", help="The video folder.")
|
||||
parser.add_argument("--saved_folder", type=str, required=True, help="The save path to the output results (csv/jsonl).")
|
||||
parser.add_argument("--cutscene_threshold", type=int, default=27, help="The threshold of ContentDetector.")
|
||||
parser.add_argument("--n_jobs", type=int, default=1, help="The number of processes.")
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
metadata_df = pd.read_json(args.video_metadata_path, lines=True)
|
||||
video_path_list = metadata_df[args.video_path_column].tolist()
|
||||
video_path_list = [os.path.join(args.video_folder, video_path) for video_path in video_path_list]
|
||||
|
||||
if not os.path.exists(args.saved_folder):
|
||||
os.makedirs(args.saved_folder, exist_ok=True)
|
||||
# The glob can be slow when there are many small jsonl files.
|
||||
saved_path_list = [os.path.join(args.saved_folder, Path(video_path).with_suffix(".jsonl")) for video_path in video_path_list]
|
||||
saved_path_list = [os.path.join(args.saved_folder, Path(video_path).stem + ".jsonl") for video_path in video_path_list]
|
||||
args_list = [
|
||||
(video_path, args.video_folder, saved_path, args.cutscene_threshold)
|
||||
(video_path, saved_path)
|
||||
for video_path, saved_path in zip(video_path_list, saved_path_list)
|
||||
]
|
||||
# Since the length of the video is not uniform, the gather operation is not performed.
|
||||
@@ -3,8 +3,9 @@ import os
|
||||
|
||||
import pandas as pd
|
||||
from natsort import natsorted
|
||||
from utils.filter import filter
|
||||
|
||||
from utils.logger import logger
|
||||
from utils.filter import filter
|
||||
|
||||
|
||||
def parse_args():
|
||||
@@ -18,12 +19,6 @@ def parse_args():
|
||||
default="video_path",
|
||||
help="The column contains the video path (an absolute path or a relative path w.r.t the video_folder).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--caption_column",
|
||||
type=str,
|
||||
default="caption",
|
||||
help="The column contains the caption.",
|
||||
)
|
||||
parser.add_argument("--video_folder", type=str, default="", help="The video folder.")
|
||||
parser.add_argument(
|
||||
"--basic_metadata_path", type=str, default=None, help="The path to the basic metadata (csv/jsonl)."
|
||||
@@ -32,13 +27,13 @@ def parse_args():
|
||||
parser.add_argument("--min_duration", type=float, default=-1, help="The minimum duration.")
|
||||
parser.add_argument("--max_duration", type=float, default=-1, help="The maximum duration.")
|
||||
parser.add_argument(
|
||||
"--aesthetic_score_metadata_path", type=str, default=None, help="The path to the video quality metadata (csv/jsonl)."
|
||||
"--asethetic_score_metadata_path", type=str, default=None, help="The path to the video quality metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_aesthetic_score", type=float, default=4.0, help="The aesthetic score threshold.")
|
||||
parser.add_argument("--min_asethetic_score", type=float, default=4.0, help="The asethetic score threshold.")
|
||||
parser.add_argument(
|
||||
"--aesthetic_score_siglip_metadata_path", type=str, default=None, help="The path to the video quality (SigLIP) metadata (csv/jsonl)."
|
||||
"--asethetic_score_siglip_metadata_path", type=str, default=None, help="The path to the video quality (SigLIP) metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_aesthetic_score_siglip", type=float, default=4.0, help="The aesthetic score (SigLIP) threshold.")
|
||||
parser.add_argument("--min_asethetic_score_siglip", type=float, default=4.0, help="The asethetic score (SigLIP) threshold.")
|
||||
parser.add_argument(
|
||||
"--text_score_metadata_path", type=str, default=None, help="The path to the video text score metadata (csv/jsonl)."
|
||||
)
|
||||
@@ -68,10 +63,10 @@ def main():
|
||||
min_resolution=args.min_resolution,
|
||||
min_duration=args.min_duration,
|
||||
max_duration=args.max_duration,
|
||||
aesthetic_score_metadata_path=args.aesthetic_score_metadata_path,
|
||||
min_aesthetic_score=args.min_aesthetic_score,
|
||||
aesthetic_score_siglip_metadata_path=args.aesthetic_score_siglip_metadata_path,
|
||||
min_aesthetic_score_siglip=args.min_aesthetic_score_siglip,
|
||||
asethetic_score_metadata_path=args.asethetic_score_metadata_path,
|
||||
min_asethetic_score=args.min_asethetic_score,
|
||||
asethetic_score_siglip_metadata_path=args.asethetic_score_siglip_metadata_path,
|
||||
min_asethetic_score_siglip=args.min_asethetic_score_siglip,
|
||||
text_score_metadata_path=args.text_score_metadata_path,
|
||||
min_text_score=args.min_text_score,
|
||||
motion_score_metadata_path=args.motion_score_metadata_path,
|
||||
@@ -82,7 +77,7 @@ def main():
|
||||
)
|
||||
filtered_video_path_list = natsorted(filtered_video_path_list)
|
||||
filtered_caption_df = raw_caption_df[raw_caption_df[args.video_path_column].isin(filtered_video_path_list)]
|
||||
train_df = filtered_caption_df.rename(columns={args.video_path_column: "file_path", args.caption_column: "text"})
|
||||
train_df = filtered_caption_df.rename(columns={"video_path": "file_path", "caption": "text"})
|
||||
train_df["file_path"] = train_df["file_path"].map(lambda x: os.path.join(args.video_folder, x))
|
||||
train_df["type"] = "video"
|
||||
train_df.to_json(args.saved_path, orient="records", force_ascii=False, indent=2)
|
||||
@@ -1,19 +1,17 @@
|
||||
"""Modified from https://github.com/JaidedAI/EasyOCR/blob/803b907/easyocr/detection.py.
|
||||
1. Disable DataParallel.
|
||||
"""
|
||||
import torch
|
||||
import torch.backends.cudnn as cudnn
|
||||
from torch.autograd import Variable
|
||||
from PIL import Image
|
||||
from collections import OrderedDict
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.backends.cudnn as cudnn
|
||||
from PIL import Image
|
||||
from torch.autograd import Variable
|
||||
|
||||
from .craft_utils import getDetBoxes, adjustResultCoordinates
|
||||
from .imgproc import resize_aspect_ratio, normalizeMeanVariance
|
||||
from .craft import CRAFT
|
||||
from .craft_utils import adjustResultCoordinates, getDetBoxes
|
||||
from .imgproc import normalizeMeanVariance, resize_aspect_ratio
|
||||
|
||||
|
||||
def copyStateDict(state_dict):
|
||||
if list(state_dict.keys())[0].startswith("module"):
|
||||
@@ -0,0 +1,42 @@
|
||||
# Modified from https://github.com/NVlabs/VILA/blob/1c88211/llava/model/multimodal_encoder/siglip_encoder.py
|
||||
# 1. Support transformers >= 4.36.2.
|
||||
import torch
|
||||
import transformers
|
||||
from packaging import version
|
||||
from transformers import AutoConfig, AutoModel, PretrainedConfig
|
||||
|
||||
from llava.model.multimodal_encoder.vision_encoder import VisionTower, VisionTowerS2
|
||||
|
||||
if version.parse(transformers.__version__) > version.parse("4.36.2"):
|
||||
from transformers import SiglipImageProcessor, SiglipVisionConfig, SiglipVisionModel
|
||||
else:
|
||||
from .siglip import SiglipImageProcessor, SiglipVisionConfig, SiglipVisionModel
|
||||
|
||||
|
||||
class SiglipVisionTower(VisionTower):
|
||||
def __init__(self, model_name_or_path: str, config: PretrainedConfig, state_dict=None):
|
||||
super().__init__(model_name_or_path, config)
|
||||
self.image_processor = SiglipImageProcessor.from_pretrained(model_name_or_path)
|
||||
self.vision_tower = SiglipVisionModel.from_pretrained(
|
||||
# TODO(ligeng): why pass config here leading to errors?
|
||||
model_name_or_path, torch_dtype=eval(config.model_dtype), state_dict=state_dict
|
||||
)
|
||||
self.is_loaded = True
|
||||
|
||||
|
||||
class SiglipVisionTowerS2(VisionTowerS2):
|
||||
def __init__(self, model_name_or_path: str, config: PretrainedConfig):
|
||||
super().__init__(model_name_or_path, config)
|
||||
self.image_processor = SiglipImageProcessor.from_pretrained(model_name_or_path)
|
||||
self.vision_tower = SiglipVisionModel.from_pretrained(
|
||||
model_name_or_path, torch_dtype=eval(config.model_dtype)
|
||||
)
|
||||
|
||||
# Make sure it crops/resizes the image to the largest scale in self.scales to maintain high-res information
|
||||
self.image_processor.size['height'] = self.image_processor.size['width'] = self.scales[-1]
|
||||
|
||||
self.is_loaded = True
|
||||
|
||||
if version.parse(transformers.__version__) <= version.parse("4.36.2"):
|
||||
AutoConfig.register("siglip_vision_model", SiglipVisionConfig)
|
||||
AutoModel.register(SiglipVisionConfig, SiglipVisionModel)
|
||||
@@ -2,10 +2,8 @@ Please rewrite the video description to be useful for AI to re-generate the vide
|
||||
1. Do not start with something similar to 'The video/scene/frame shows' or "In this video/scene/frame".
|
||||
2. Remove the subjective content deviates from describing the visual content of the video. For instance, a sentence like "It gives a feeling of ease and tranquility and makes people feel comfortable" is considered subjective.
|
||||
3. Remove the non-existent description that does not in the visual content of the video, For instance, a sentence like "There is no visible detail that could be used to identify the individual beyond what is shown." is considered as the non-existent description.
|
||||
4. The rewritten description should include the main subject (person, object, animal, or none) actions and their attributes or status sequence, the background (the objects, location, weather, and time).
|
||||
5. If the original description includes the view shot, camera movement and the video style, the rewritten description should also include them. If not, there is no need to invent them on your own.
|
||||
6. Here are some examples of good descriptions: 1) A stylish woman walks down a Tokyo street filled with warm glowing neon and animated city signage. She wears a black leather jacket, a long red dress, and black boots, and carries a black purse. She wears sunglasses and red lipstick. She walks confidently and casually. The street is damp and reflective, creating a mirror effect of the colorful lights. Many pedestrians walk about. 2) A large orange octopus is seen resting on the bottom of the ocean floor, blending in with the sandy and rocky terrain. Its tentacles are spread out around its body, and its eyes are closed. The octopus is unaware of a king crab that is crawling towards it from behind a rock, its claws raised and ready to attack. The crab is brown and spiny, with long legs and antennae. The scene is captured from a wide angle, showing the vastness and depth of the ocean. The water is clear and blue, with rays of sunlight filtering through. The shot is sharp and crisp, with a high dynamic range. The octopus and the crab are in focus, while the background is slightly blurred, creating a depth of field effect.
|
||||
7. Output with the following json format:
|
||||
4. Here are some examples of good descriptions: 1) A stylish woman walks down a Tokyo street filled with warm glowing neon and animated city signage. She wears a black leather jacket, a long red dress, and black boots, and carries a black purse. She wears sunglasses and red lipstick. She walks confidently and casually. The street is damp and reflective, creating a mirror effect of the colorful lights. Many pedestrians walk about. 2) A large orange octopus is seen resting on the bottom of the ocean floor, blending in with the sandy and rocky terrain. Its tentacles are spread out around its body, and its eyes are closed. The octopus is unaware of a king crab that is crawling towards it from behind a rock, its claws raised and ready to attack. The crab is brown and spiny, with long legs and antennae. The scene is captured from a wide angle, showing the vastness and depth of the ocean. The water is clear and blue, with rays of sunlight filtering through. The shot is sharp and crisp, with a high dynamic range. The octopus and the crab are in focus, while the background is slightly blurred, creating a depth of field effect.
|
||||
5. Output with the following json format:
|
||||
{"rewritten description": "your rewritten description here"}
|
||||
|
||||
Here is the video description:
|
||||
@@ -4,4 +4,6 @@ git+https://github.com/openai/CLIP.git
|
||||
natsort
|
||||
joblib
|
||||
scenedetect
|
||||
av
|
||||
av
|
||||
# https://github.com/NVlabs/VILA/issues/78#issuecomment-2195568292
|
||||
numpy<2.0.0
|
||||
@@ -0,0 +1,41 @@
|
||||
META_FILE_PATH="datasets/panda_70m/videos_clips/data/meta_file_info.jsonl"
|
||||
VIDEO_FOLDER="datasets/panda_70m/videos_clips/data/"
|
||||
VIDEO_QUALITY_SAVED_PATH="datasets/panda_70m/videos_clips/meta_quality_info_siglip.jsonl"
|
||||
MIN_ASETHETIC_SCORE_SIGLIP=4.0
|
||||
TEXT_SAVED_PATH="datasets/panda_70m/videos_clips/meta_text_info.jsonl"
|
||||
MIN_TEXT_SCORE=0.02
|
||||
MOTION_SAVED_PATH="datasets/panda_70m/videos_clips/meta_motion_info.jsonl"
|
||||
|
||||
python -m utils.get_meta_file \
|
||||
--video_folder $VIDEO_FOLDER \
|
||||
--saved_path $META_FILE_PATH
|
||||
|
||||
# Get the asethetic score (SigLIP) of all videos
|
||||
accelerate launch compute_video_quality.py \
|
||||
--video_metadata_path $META_FILE_PATH \
|
||||
--video_folder $VIDEO_FOLDER \
|
||||
--metrics "AestheticScoreSigLIP" \
|
||||
--frame_sample_method uniform \
|
||||
--num_sampled_frames 4 \
|
||||
--saved_freq 10 \
|
||||
--saved_path $VIDEO_QUALITY_SAVED_PATH \
|
||||
--batch_size 4
|
||||
|
||||
# Get the text score of all videos filtered by the video quality score.
|
||||
accelerate launch compute_text_score.py \
|
||||
--video_metadata_path $META_FILE_PATH \
|
||||
--video_folder $VIDEO_FOLDER \
|
||||
--saved_freq 10 \
|
||||
--saved_path $TEXT_SAVED_PATH \
|
||||
--asethetic_score_siglip_metadata_path $VIDEO_QUALITY_SAVED_PATH \
|
||||
--min_asethetic_score_siglip $MIN_ASETHETIC_SCORE_SIGLIP
|
||||
|
||||
# Get the motion score of all videos filtered by the video quality score and text score.
|
||||
python compute_motion_score.py \
|
||||
--video_metadata_path $META_FILE_PATH \
|
||||
--video_folder $VIDEO_FOLDER \
|
||||
--saved_freq 10 \
|
||||
--saved_path $MOTION_SAVED_PATH \
|
||||
--n_jobs 8 \
|
||||
--text_score_metadata_path $TEXT_SAVED_PATH \
|
||||
--min_text_score $MIN_TEXT_SCORE
|
||||
@@ -0,0 +1,52 @@
|
||||
META_FILE_PATH="datasets/panda_70m/videos_clips/data/meta_file_info.jsonl"
|
||||
VIDEO_FOLDER="datasets/panda_70m/videos_clips/data/"
|
||||
MOTION_SAVED_PATH="datasets/panda_70m/videos_clips/meta_motion_info.jsonl"
|
||||
MIN_MOTION_SCORE=2
|
||||
VIDEO_CAPTION_SAVED_PATH="datasets/panda_70m/meta_caption_info_vila_8b.jsonl"
|
||||
REWRITTEN_VIDEO_CAPTION_SAVED_PATH="datasets/panda_70m/meta_caption_info_vila_8b_rewritten.jsonl"
|
||||
VIDEOCLIPXL_SCORE_SAVED_PATH="datasets/panda_70m/meta_caption_info_vila_8b_rewritten_videoclipxl.jsonl"
|
||||
MIN_VIDEOCLIPXL_SCORE=0.20
|
||||
TRAIN_SAVED_PATH="datasets/panda_70m/train_panda_70m.json"
|
||||
# Manually download Efficient-Large-Model/Llama-3-VILA1.5-8b-AWQ to VILA_MODEL_PATH.
|
||||
# Manually download meta-llama/Meta-Llama-3-8B-Instruct to REWRITE_MODEL_PATH.
|
||||
|
||||
# Use VILA1.5-AWQ to perform recaptioning.
|
||||
accelerate launch vila_video_recaptioning.py \
|
||||
--video_metadata_path ${META_FILE_PATH} \
|
||||
--video_folder ${VIDEO_FOLDER} \
|
||||
--model_path ${VILA_MODEL_PATH} \
|
||||
--precision "W4A16" \
|
||||
--saved_path $VIDEO_CAPTION_SAVED_PATH \
|
||||
--saved_freq 1 \
|
||||
--motion_score_metadata_path $MOTION_SAVED_PATH \
|
||||
--min_motion_score $MIN_MOTION_SCORE
|
||||
|
||||
# Rewrite video captions (optional).
|
||||
python caption_rewrite.py \
|
||||
--video_metadata_path $VIDEO_CAPTION_SAVED_PATH \
|
||||
--batch_size 4096 \
|
||||
--model_name $REWRITE_MODEL_PATH \
|
||||
--prompt prompt/rewrite.txt \
|
||||
--prefix '"rewritten description": ' \
|
||||
--saved_path $REWRITTEN_VIDEO_CAPTION_SAVED_PATH \
|
||||
--saved_freq 1
|
||||
|
||||
# Compute caption-video alignment (optional).
|
||||
accelerate launch compute_video_quality.py \
|
||||
--video_metadata_path $REWRITTEN_VIDEO_CAPTION_SAVED_PATH \
|
||||
--caption_column caption \
|
||||
--video_folder $VIDEO_FOLDER \
|
||||
--frame_sample_method uniform \
|
||||
--num_sampled_frames 8 \
|
||||
--metrics VideoCLIPXLScore \
|
||||
--batch_size 4 \
|
||||
--saved_path $VIDEOCLIPXL_SCORE_SAVED_PATH \
|
||||
--saved_freq 10
|
||||
|
||||
# Get the final train file.
|
||||
python filter_meta_train.py \
|
||||
--caption_metadata_path $REWRITTEN_VIDEO_CAPTION_SAVED_PATH \
|
||||
--video_folder=$VIDEO_FOLDER \
|
||||
--videoclipxl_score_metadata_path $VIDEOCLIPXL_SCORE_SAVED_PATH \
|
||||
--min_videoclipxl_score $MIN_VIDEOCLIPXL_SCORE \
|
||||
--saved_path=$TRAIN_SAVED_PATH
|
||||
@@ -1,42 +1,41 @@
|
||||
import ast
|
||||
from typing import Optional
|
||||
import os
|
||||
|
||||
import pandas as pd
|
||||
|
||||
from .logger import logger
|
||||
|
||||
|
||||
# Ensure each item in the video_path_list matches the paths in the video_path column of the metadata.
|
||||
def filter(
|
||||
video_path_list: list[str],
|
||||
basic_metadata_path: Optional[str] = None,
|
||||
min_resolution: float = 720*1280,
|
||||
min_duration: float = -1,
|
||||
max_duration: float = -1,
|
||||
aesthetic_score_metadata_path: Optional[str] = None,
|
||||
min_aesthetic_score: float = 4,
|
||||
aesthetic_score_siglip_metadata_path: Optional[str] = None,
|
||||
min_aesthetic_score_siglip: float = 4,
|
||||
text_score_metadata_path: Optional[str] = None,
|
||||
min_text_score: float = 0.02,
|
||||
motion_score_metadata_path: Optional[str] = None,
|
||||
min_motion_score: float = 2,
|
||||
max_motion_score: float = 999999,
|
||||
videoclipxl_score_metadata_path: Optional[str] = None,
|
||||
min_videoclipxl_score: float = 0.20,
|
||||
semantic_consistency_score_metadata_path: Optional[list[str]] = None,
|
||||
min_semantic_consistency_score: float = 0.80,
|
||||
video_path_column: str = "video_path"
|
||||
video_path_list,
|
||||
basic_metadata_path=None,
|
||||
min_resolution=0,
|
||||
min_duration=-1,
|
||||
max_duration=-1,
|
||||
asethetic_score_metadata_path=None,
|
||||
min_asethetic_score=4,
|
||||
asethetic_score_siglip_metadata_path=None,
|
||||
min_asethetic_score_siglip=4,
|
||||
text_score_metadata_path=None,
|
||||
min_text_score=0.02,
|
||||
motion_score_metadata_path=None,
|
||||
min_motion_score=2,
|
||||
videoclipxl_score_metadata_path=None,
|
||||
min_videoclipxl_score=0.20,
|
||||
video_path_column="video_path",
|
||||
):
|
||||
video_path_list = [os.path.basename(video_path) for video_path in video_path_list]
|
||||
|
||||
if basic_metadata_path is not None:
|
||||
if basic_metadata_path.endswith(".csv"):
|
||||
basic_df = pd.read_csv(basic_metadata_path)
|
||||
elif basic_metadata_path.endswith(".jsonl"):
|
||||
basic_df = pd.read_json(basic_metadata_path, lines=True)
|
||||
|
||||
|
||||
basic_df["resolution"] = basic_df["frame_size"].apply(lambda x: x[0] * x[1])
|
||||
filtered_basic_df = basic_df[basic_df["resolution"] < min_resolution]
|
||||
filtered_video_path_list = filtered_basic_df[video_path_column].tolist()
|
||||
filtered_video_path_list = [os.path.basename(video_path) for video_path in filtered_video_path_list]
|
||||
|
||||
video_path_list = list(set(video_path_list).difference(set(filtered_video_path_list)))
|
||||
logger.info(
|
||||
@@ -47,6 +46,7 @@ def filter(
|
||||
if min_duration != -1:
|
||||
filtered_basic_df = basic_df[basic_df["duration"] < min_duration]
|
||||
filtered_video_path_list = filtered_basic_df[video_path_column].tolist()
|
||||
filtered_video_path_list = [os.path.basename(video_path) for video_path in filtered_video_path_list]
|
||||
|
||||
video_path_list = list(set(video_path_list).difference(set(filtered_video_path_list)))
|
||||
logger.info(
|
||||
@@ -57,6 +57,7 @@ def filter(
|
||||
if max_duration != -1:
|
||||
filtered_basic_df = basic_df[basic_df["duration"] > max_duration]
|
||||
filtered_video_path_list = filtered_basic_df[video_path_column].tolist()
|
||||
filtered_video_path_list = [os.path.basename(video_path) for video_path in filtered_video_path_list]
|
||||
|
||||
video_path_list = list(set(video_path_list).difference(set(filtered_video_path_list)))
|
||||
logger.info(
|
||||
@@ -64,48 +65,50 @@ def filter(
|
||||
f"with duration greater than {max_duration}."
|
||||
)
|
||||
|
||||
if aesthetic_score_metadata_path is not None:
|
||||
if aesthetic_score_metadata_path.endswith(".csv"):
|
||||
aesthetic_score_df = pd.read_csv(aesthetic_score_metadata_path)
|
||||
elif aesthetic_score_metadata_path.endswith(".jsonl"):
|
||||
aesthetic_score_df = pd.read_json(aesthetic_score_metadata_path, lines=True)
|
||||
if asethetic_score_metadata_path is not None:
|
||||
if asethetic_score_metadata_path.endswith(".csv"):
|
||||
asethetic_score_df = pd.read_csv(asethetic_score_metadata_path)
|
||||
elif asethetic_score_metadata_path.endswith(".jsonl"):
|
||||
asethetic_score_df = pd.read_json(asethetic_score_metadata_path, lines=True)
|
||||
|
||||
# In pandas, csv will save lists as strings, whereas jsonl will not.
|
||||
aesthetic_score_df["aesthetic_score"] = aesthetic_score_df["aesthetic_score"].apply(
|
||||
asethetic_score_df["aesthetic_score"] = asethetic_score_df["aesthetic_score"].apply(
|
||||
lambda x: ast.literal_eval(x) if isinstance(x, str) else x
|
||||
)
|
||||
aesthetic_score_df["aesthetic_score_mean"] = aesthetic_score_df["aesthetic_score"].apply(lambda x: sum(x) / len(x))
|
||||
filtered_aesthetic_score_df = aesthetic_score_df[aesthetic_score_df["aesthetic_score_mean"] < min_aesthetic_score]
|
||||
filtered_video_path_list = filtered_aesthetic_score_df[video_path_column].tolist()
|
||||
asethetic_score_df["aesthetic_score_mean"] = asethetic_score_df["aesthetic_score"].apply(lambda x: sum(x) / len(x))
|
||||
filtered_asethetic_score_df = asethetic_score_df[asethetic_score_df["aesthetic_score_mean"] < min_asethetic_score]
|
||||
filtered_video_path_list = filtered_asethetic_score_df[video_path_column].tolist()
|
||||
filtered_video_path_list = [os.path.basename(video_path) for video_path in filtered_video_path_list]
|
||||
|
||||
video_path_list = list(set(video_path_list).difference(set(filtered_video_path_list)))
|
||||
logger.info(
|
||||
f"Load {aesthetic_score_metadata_path} ({len(aesthetic_score_df)}) and filter {len(filtered_video_path_list)} videos "
|
||||
f"with aesthetic score less than {min_aesthetic_score}."
|
||||
f"Load {asethetic_score_metadata_path} ({len(asethetic_score_df)}) and filter {len(filtered_video_path_list)} videos "
|
||||
f"with aesthetic score less than {min_asethetic_score}."
|
||||
)
|
||||
|
||||
if aesthetic_score_siglip_metadata_path is not None:
|
||||
if aesthetic_score_siglip_metadata_path.endswith(".csv"):
|
||||
aesthetic_score_siglip_df = pd.read_csv(aesthetic_score_siglip_metadata_path)
|
||||
elif aesthetic_score_siglip_metadata_path.endswith(".jsonl"):
|
||||
aesthetic_score_siglip_df = pd.read_json(aesthetic_score_siglip_metadata_path, lines=True)
|
||||
|
||||
if asethetic_score_siglip_metadata_path is not None:
|
||||
if asethetic_score_siglip_metadata_path.endswith(".csv"):
|
||||
asethetic_score_siglip_df = pd.read_csv(asethetic_score_siglip_metadata_path)
|
||||
elif asethetic_score_siglip_metadata_path.endswith(".jsonl"):
|
||||
asethetic_score_siglip_df = pd.read_json(asethetic_score_siglip_metadata_path, lines=True)
|
||||
|
||||
# In pandas, csv will save lists as strings, whereas jsonl will not.
|
||||
aesthetic_score_siglip_df["aesthetic_score_siglip"] = aesthetic_score_siglip_df["aesthetic_score_siglip"].apply(
|
||||
asethetic_score_siglip_df["aesthetic_score_siglip"] = asethetic_score_siglip_df["aesthetic_score_siglip"].apply(
|
||||
lambda x: ast.literal_eval(x) if isinstance(x, str) else x
|
||||
)
|
||||
aesthetic_score_siglip_df["aesthetic_score_siglip_mean"] = aesthetic_score_siglip_df["aesthetic_score_siglip"].apply(
|
||||
asethetic_score_siglip_df["aesthetic_score_siglip_mean"] = asethetic_score_siglip_df["aesthetic_score_siglip"].apply(
|
||||
lambda x: sum(x) / len(x)
|
||||
)
|
||||
filtered_aesthetic_score_siglip_df = aesthetic_score_siglip_df[
|
||||
aesthetic_score_siglip_df["aesthetic_score_siglip_mean"] < min_aesthetic_score_siglip
|
||||
filtered_asethetic_score_siglip_df = asethetic_score_siglip_df[
|
||||
asethetic_score_siglip_df["aesthetic_score_siglip_mean"] < min_asethetic_score_siglip
|
||||
]
|
||||
filtered_video_path_list = filtered_aesthetic_score_siglip_df[video_path_column].tolist()
|
||||
filtered_video_path_list = filtered_asethetic_score_siglip_df[video_path_column].tolist()
|
||||
filtered_video_path_list = [os.path.basename(video_path) for video_path in filtered_video_path_list]
|
||||
|
||||
video_path_list = list(set(video_path_list).difference(set(filtered_video_path_list)))
|
||||
logger.info(
|
||||
f"Load {aesthetic_score_siglip_metadata_path} ({len(aesthetic_score_siglip_df)}) and filter {len(filtered_video_path_list)} videos "
|
||||
f"with aesthetic score (SigLIP) less than {min_aesthetic_score_siglip}."
|
||||
f"Load {asethetic_score_siglip_metadata_path} ({len(asethetic_score_siglip_df)}) and filter {len(filtered_video_path_list)} videos "
|
||||
f"with aesthetic score (SigLIP) less than {min_asethetic_score_siglip}."
|
||||
)
|
||||
|
||||
if text_score_metadata_path is not None:
|
||||
@@ -116,6 +119,7 @@ def filter(
|
||||
|
||||
filtered_text_score_df = text_score_df[text_score_df["text_score"] > min_text_score]
|
||||
filtered_video_path_list = filtered_text_score_df[video_path_column].tolist()
|
||||
filtered_video_path_list = [os.path.basename(video_path) for video_path in filtered_video_path_list]
|
||||
|
||||
video_path_list = list(set(video_path_list).difference(set(filtered_video_path_list)))
|
||||
logger.info(
|
||||
@@ -128,24 +132,16 @@ def filter(
|
||||
motion_score_df = pd.read_csv(motion_score_metadata_path)
|
||||
elif motion_score_metadata_path.endswith(".jsonl"):
|
||||
motion_score_df = pd.read_json(motion_score_metadata_path, lines=True)
|
||||
|
||||
|
||||
filtered_motion_score_df = motion_score_df[motion_score_df["motion_score"] < min_motion_score]
|
||||
filtered_video_path_list = filtered_motion_score_df[video_path_column].tolist()
|
||||
filtered_video_path_list = [os.path.basename(video_path) for video_path in filtered_video_path_list]
|
||||
|
||||
video_path_list = list(set(video_path_list).difference(set(filtered_video_path_list)))
|
||||
logger.info(
|
||||
f"Load {motion_score_metadata_path} ({len(motion_score_df)}) and filter {len(filtered_video_path_list)} videos "
|
||||
f"with motion score smaller than {min_motion_score}."
|
||||
)
|
||||
|
||||
filtered_motion_score_df = motion_score_df[motion_score_df["motion_score"] > max_motion_score]
|
||||
filtered_video_path_list = filtered_motion_score_df[video_path_column].tolist()
|
||||
|
||||
video_path_list = list(set(video_path_list).difference(set(filtered_video_path_list)))
|
||||
logger.info(
|
||||
f"Load {motion_score_metadata_path} ({len(motion_score_df)}) and filter {len(filtered_video_path_list)} videos "
|
||||
f"with motion score greater than {min_motion_score}."
|
||||
)
|
||||
|
||||
if videoclipxl_score_metadata_path is not None:
|
||||
if videoclipxl_score_metadata_path.endswith(".csv"):
|
||||
@@ -155,28 +151,12 @@ def filter(
|
||||
|
||||
filtered_videoclipxl_score_df = videoclipxl_score_df[videoclipxl_score_df["videoclipxl_score"] < min_videoclipxl_score]
|
||||
filtered_video_path_list = filtered_videoclipxl_score_df[video_path_column].tolist()
|
||||
filtered_video_path_list = [os.path.basename(video_path) for video_path in filtered_video_path_list]
|
||||
|
||||
video_path_list = list(set(video_path_list).difference(set(filtered_video_path_list)))
|
||||
logger.info(
|
||||
f"Load {videoclipxl_score_metadata_path} ({len(videoclipxl_score_df)}) and "
|
||||
f"filter {len(filtered_video_path_list)} videos with mixclip score smaller than {min_videoclipxl_score}."
|
||||
)
|
||||
|
||||
if semantic_consistency_score_metadata_path is not None:
|
||||
for f in semantic_consistency_score_metadata_path:
|
||||
if f.endswith(".csv"):
|
||||
semantic_consistency_score_df = pd.read_csv(f)
|
||||
elif f.endswith(".jsonl"):
|
||||
semantic_consistency_score_df = pd.read_json(f, lines=True)
|
||||
filtered_semantic_consistency_score_df = semantic_consistency_score_df[
|
||||
semantic_consistency_score_df["similarity_cross_frame"].apply(lambda x: min(x) < min_semantic_consistency_score)
|
||||
]
|
||||
filtered_video_path_list = filtered_semantic_consistency_score_df[video_path_column].tolist()
|
||||
|
||||
video_path_list = list(set(video_path_list).difference(set(filtered_video_path_list)))
|
||||
logger.info(
|
||||
f"Load {f} ({len(semantic_consistency_score_df)}) and filter {len(filtered_video_path_list)} videos "
|
||||
f"with the minimum semantic consistency score smaller than {min_semantic_consistency_score}."
|
||||
)
|
||||
|
||||
return video_path_list
|
||||
@@ -1,13 +1,12 @@
|
||||
import argparse
|
||||
import json
|
||||
import os
|
||||
from multiprocessing import Manager, Pool
|
||||
from pathlib import Path
|
||||
import glob
|
||||
import json
|
||||
from multiprocessing import Pool, Manager
|
||||
|
||||
import pandas as pd
|
||||
from natsort import index_natsorted
|
||||
|
||||
from .get_meta_file import parallel_rglob
|
||||
from .logger import logger
|
||||
|
||||
|
||||
@@ -21,10 +20,9 @@ def process_file(file_path, shared_list):
|
||||
def parse_args():
|
||||
parser = argparse.ArgumentParser(description="Gather all jsonl files in a folder (meta_folder) to a single jsonl file (meta_file_path).")
|
||||
parser.add_argument("--meta_folder", type=str, required=True)
|
||||
parser.add_argument("--video_path_column", type=str, default="video_path")
|
||||
parser.add_argument("--meta_file_path", type=str, required=True)
|
||||
parser.add_argument("--video_path_column", type=str, default="video_path")
|
||||
parser.add_argument("--n_jobs", type=int, default=1)
|
||||
parser.add_argument("--recursive", action="store_true", help="Whether to search sub-folders recursively.")
|
||||
|
||||
args = parser.parse_args()
|
||||
return args
|
||||
@@ -33,13 +31,7 @@ def parse_args():
|
||||
def main():
|
||||
args = parse_args()
|
||||
|
||||
if not os.path.exists(args.meta_folder):
|
||||
raise ValueError(f"The meta_folder {args.meta_folder} does not exist.")
|
||||
meta_folder = Path(args.meta_folder)
|
||||
if args.recursive:
|
||||
jsonl_files = [str(file) for file in parallel_rglob(meta_folder, f"*.jsonl", max_workers=args.n_jobs)]
|
||||
else:
|
||||
jsonl_files = [str(file) for file in meta_folder.glob(f"*.jsonl")]
|
||||
jsonl_files = glob.glob(os.path.join(args.meta_folder, "*.jsonl"))
|
||||
|
||||
with Manager() as manager:
|
||||
shared_list = manager.list()
|
||||
@@ -1,40 +1,17 @@
|
||||
import argparse
|
||||
import os
|
||||
from pathlib import Path
|
||||
|
||||
import pandas as pd
|
||||
from natsort import natsorted
|
||||
from tqdm import tqdm
|
||||
|
||||
from .logger import logger
|
||||
|
||||
ALL_VIDEO_EXT = set(["mp4", "webm", "mkv", "avi", "flv", "mov", "rmvb"])
|
||||
|
||||
ALL_VIDEO_EXT = set(["mp4", "webm", "mkv", "avi", "flv", "mov"])
|
||||
ALL_IMGAE_EXT = set(["png", "webp", "jpg", "jpeg", "bmp", "gif"])
|
||||
|
||||
|
||||
def get_relative_file_paths(directory, recursive=False, ext_set=None):
|
||||
"""Get the relative paths of subfiles (recursively) in the directory that match the extension set.
|
||||
"""
|
||||
if not recursive:
|
||||
for entry in os.scandir(directory):
|
||||
if entry.is_file():
|
||||
file_name = entry.name
|
||||
if ext_set is not None:
|
||||
ext = os.path.splitext(file_name)[1][1:].lower()
|
||||
if ext in ext_set:
|
||||
yield file_name
|
||||
else:
|
||||
yield file_name
|
||||
else:
|
||||
for root, _, files in os.walk(directory):
|
||||
for file in files:
|
||||
relative_path = os.path.relpath(os.path.join(root, file), directory)
|
||||
if ext_set is not None:
|
||||
ext = os.path.splitext(file)[1][1:].lower()
|
||||
if ext in ext_set:
|
||||
yield relative_path
|
||||
else:
|
||||
yield relative_path
|
||||
|
||||
|
||||
def parse_args():
|
||||
parser = argparse.ArgumentParser(description="Compute scores of uniform sampled frames from videos.")
|
||||
parser.add_argument(
|
||||
@@ -65,19 +42,27 @@ def main():
|
||||
raise ValueError("Either video_folder or image_folder should be specified in the arguments.")
|
||||
if args.video_folder is not None and args.image_folder is not None:
|
||||
raise ValueError("Both video_folder and image_folder can not be specified in the arguments at the same time.")
|
||||
if args.image_folder is None and not os.path.exists(args.video_folder):
|
||||
raise ValueError(f"The video_folder {args.video_folder} does not exist.")
|
||||
if args.video_folder is None and not os.path.exists(args.image_folder):
|
||||
raise ValueError(f"The image_folder {args.image_folder} does not exist.")
|
||||
|
||||
# Use the path name instead of the file name as video_path/image_path (unique ID).
|
||||
if args.video_folder is not None:
|
||||
video_path_list = list(get_relative_file_paths(args.video_folder, recursive=args.recursive, ext_set=ALL_VIDEO_EXT))
|
||||
video_path_list = []
|
||||
video_folder = Path(args.video_folder)
|
||||
for ext in tqdm(list(ALL_VIDEO_EXT)):
|
||||
if args.recursive:
|
||||
video_path_list += [str(file.relative_to(video_folder)) for file in video_folder.rglob(f"*.{ext}")]
|
||||
else:
|
||||
video_path_list += [str(file.relative_to(video_folder)) for file in video_folder.glob(f"*.{ext}")]
|
||||
video_path_list = natsorted(video_path_list)
|
||||
meta_file_df = pd.DataFrame({args.video_path_column: video_path_list})
|
||||
|
||||
if args.image_folder is not None:
|
||||
image_path_list = list(get_relative_file_paths(args.image_folder, recursive=args.recursive, ext_set=ALL_IMGAE_EXT))
|
||||
image_path_list = []
|
||||
image_folder = Path(args.image_folder)
|
||||
for ext in tqdm(list(ALL_IMGAE_EXT)):
|
||||
if args.recursive:
|
||||
image_path_list += [str(file.relative_to(image_folder)) for file in image_folder.rglob(f"*.{ext}")]
|
||||
else:
|
||||
image_path_list += [str(file.relative_to(image_folder)) for file in image_folder.glob(f"*.{ext}")]
|
||||
image_path_list = natsorted(image_path_list)
|
||||
meta_file_df = pd.DataFrame({args.image_path_column: image_path_list})
|
||||
|
||||
@@ -223,7 +223,6 @@ class CLIPScore:
|
||||
if __name__ == "__main__":
|
||||
from torch.utils.data import DataLoader
|
||||
from tqdm import tqdm
|
||||
|
||||
from .video_dataset import VideoDataset, collate_fn
|
||||
|
||||
aesthetic_score = AestheticScore(device="cuda")
|
||||
@@ -2,14 +2,12 @@ import hashlib
|
||||
import os
|
||||
import urllib
|
||||
import warnings
|
||||
from typing import Any, List, Union
|
||||
|
||||
import torch
|
||||
from PIL import Image
|
||||
from typing import Any, Union, List
|
||||
from pkg_resources import packaging
|
||||
from torch import nn
|
||||
from torchvision.transforms import (CenterCrop, Compose, Normalize, Resize,
|
||||
ToTensor)
|
||||
import torch
|
||||
from PIL import Image
|
||||
from torchvision.transforms import Compose, Resize, CenterCrop, ToTensor, Normalize
|
||||
from tqdm import tqdm
|
||||
|
||||
from .model_longclip import build_model
|
||||
@@ -6,8 +6,12 @@ from typing import Final
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from transformers import (SiglipImageProcessor, SiglipVisionConfig,
|
||||
SiglipVisionModel, logging)
|
||||
from transformers import (
|
||||
SiglipImageProcessor,
|
||||
SiglipVisionConfig,
|
||||
SiglipVisionModel,
|
||||
logging,
|
||||
)
|
||||
from transformers.image_processing_utils import BatchFeature
|
||||
from transformers.modeling_outputs import ImageClassifierOutputWithNoAttention
|
||||
|
||||
@@ -1,11 +1,9 @@
|
||||
import os
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
from .simple_tokenizer import SimpleTokenizer as _Tokenizer
|
||||
from .viclip import ViCLIP
|
||||
import torch
|
||||
import numpy as np
|
||||
import cv2
|
||||
import os
|
||||
|
||||
|
||||
def get_viclip(size='l',
|
||||
@@ -1,15 +1,15 @@
|
||||
import logging
|
||||
import math
|
||||
import os
|
||||
import logging
|
||||
|
||||
import torch
|
||||
from einops import rearrange
|
||||
from torch import nn
|
||||
import math
|
||||
|
||||
# from .criterions import VTC_VTM_Loss
|
||||
from .simple_tokenizer import SimpleTokenizer as _Tokenizer
|
||||
from .viclip_text import clip_text_b16, clip_text_l14
|
||||
from .viclip_vision import clip_joint_b16, clip_joint_l14
|
||||
from .viclip_vision import clip_joint_l14, clip_joint_b16
|
||||
from .viclip_text import clip_text_l14, clip_text_b16
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
@@ -1,16 +1,15 @@
|
||||
import functools
|
||||
import logging
|
||||
import os
|
||||
import logging
|
||||
from collections import OrderedDict
|
||||
from pkg_resources import packaging
|
||||
from .simple_tokenizer import SimpleTokenizer as _Tokenizer
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
import torch.utils.checkpoint as checkpoint
|
||||
from pkg_resources import packaging
|
||||
from torch import nn
|
||||
|
||||
from .simple_tokenizer import SimpleTokenizer as _Tokenizer
|
||||
import torch.utils.checkpoint as checkpoint
|
||||
import functools
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
@@ -1,14 +1,15 @@
|
||||
#!/usr/bin/env python
|
||||
import logging
|
||||
import os
|
||||
import logging
|
||||
from collections import OrderedDict
|
||||
|
||||
import torch
|
||||
import torch.utils.checkpoint as checkpoint
|
||||
from torch import nn
|
||||
from einops import rearrange
|
||||
from timm.models.layers import DropPath
|
||||
from timm.models.registry import register_model
|
||||
from torch import nn
|
||||
|
||||
import torch.utils.checkpoint as checkpoint
|
||||
|
||||
# from models.utils import load_temp_embed_with_mismatch
|
||||
|
||||
@@ -339,9 +340,9 @@ def interpolate_pos_embed_vit(state_dict, new_model):
|
||||
|
||||
if __name__ == '__main__':
|
||||
import time
|
||||
|
||||
from fvcore.nn import FlopCountAnalysis
|
||||
from fvcore.nn import flop_count_table
|
||||
import numpy as np
|
||||
from fvcore.nn import FlopCountAnalysis, flop_count_table
|
||||
|
||||
seed = 4217
|
||||
np.random.seed(seed)
|
||||
@@ -1,16 +1,16 @@
|
||||
import os
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
from pathlib import Path
|
||||
|
||||
from func_timeout import FunctionTimedOut, func_timeout
|
||||
from func_timeout import func_timeout, FunctionTimedOut
|
||||
from PIL import Image
|
||||
from torch.utils.data import DataLoader, Dataset
|
||||
from torch.utils.data import Dataset, DataLoader
|
||||
|
||||
from .logger import logger
|
||||
from .video_utils import extract_frames
|
||||
|
||||
|
||||
ALL_VIDEO_EXT = set([".mp4", ".webm", ".mkv", ".avi", ".flv", ".mov", ".ts"])
|
||||
ALL_VIDEO_EXT = set(["mp4", "webm", "mkv", "avi", "flv", "mov"])
|
||||
VIDEO_READER_TIMEOUT = 300
|
||||
|
||||
|
||||
@@ -30,7 +30,7 @@ class VideoDataset(Dataset):
|
||||
text_column: Optional[str] = None,
|
||||
sample_method: str = "mid",
|
||||
num_sampled_frames: int = 1,
|
||||
sample_stride: Optional[int] = None
|
||||
num_sample_stride: Optional[int] = None
|
||||
):
|
||||
length = len(dataset_inputs[list(dataset_inputs.keys())[0]])
|
||||
if not all(len(v) == length for v in dataset_inputs.values()):
|
||||
@@ -46,7 +46,7 @@ class VideoDataset(Dataset):
|
||||
|
||||
self.sample_method = sample_method
|
||||
self.num_sampled_frames = num_sampled_frames
|
||||
self.sample_stride = sample_stride
|
||||
self.num_sample_stride = num_sample_stride
|
||||
|
||||
def __getitem__(self, index):
|
||||
video_path = self.video_path_list[index]
|
||||
@@ -61,7 +61,7 @@ class VideoDataset(Dataset):
|
||||
else:
|
||||
# It is a trick to deal with decord hanging when reading some abnormal videos.
|
||||
try:
|
||||
sample_args = (video_path, self.sample_method, self.num_sampled_frames, self.sample_stride)
|
||||
sample_args = (video_path, self.sample_method, self.num_sampled_frames, self.num_sample_stride)
|
||||
sampled_frame_idx_list, sampled_frame_list = func_timeout(
|
||||
VIDEO_READER_TIMEOUT, extract_frames, args=sample_args
|
||||
)
|
||||
@@ -0,0 +1,44 @@
|
||||
import gc
|
||||
import random
|
||||
from contextlib import contextmanager
|
||||
from typing import List, Tuple, Optional
|
||||
|
||||
import numpy as np
|
||||
from decord import VideoReader
|
||||
from PIL import Image
|
||||
|
||||
|
||||
@contextmanager
|
||||
def video_reader(*args, **kwargs):
|
||||
"""A context manager to solve the memory leak of decord.
|
||||
"""
|
||||
vr = VideoReader(*args, **kwargs)
|
||||
try:
|
||||
yield vr
|
||||
finally:
|
||||
del vr
|
||||
gc.collect()
|
||||
|
||||
|
||||
def extract_frames(
|
||||
video_path: str,
|
||||
sample_method: str = "mid",
|
||||
num_sampled_frames: int = -1,
|
||||
sample_stride: int = -1,
|
||||
**kwargs
|
||||
) -> Optional[Tuple[List[int], List[Image.Image]]]:
|
||||
with video_reader(video_path, num_threads=2, **kwargs) as vr:
|
||||
if sample_method == "mid":
|
||||
sampled_frame_idx_list = [len(vr) // 2]
|
||||
elif sample_method == "uniform":
|
||||
sampled_frame_idx_list = np.linspace(0, len(vr), num_sampled_frames, endpoint=False, dtype=int)
|
||||
elif sample_method == "random":
|
||||
clip_length = min(len(vr), (num_sampled_frames - 1) * sample_stride + 1)
|
||||
start_idx = random.randint(0, len(vr) - clip_length)
|
||||
sampled_frame_idx_list = np.linspace(start_idx, start_idx + clip_length - 1, num_sampled_frames, dtype=int)
|
||||
else:
|
||||
raise ValueError(f"The sample_method {sample_method} must be mid, uniform or random.")
|
||||
sampled_frame_list = vr.get_batch(sampled_frame_idx_list).asnumpy()
|
||||
sampled_frame_list = [Image.fromarray(frame) for frame in sampled_frame_list]
|
||||
|
||||
return list(sampled_frame_idx_list), sampled_frame_list
|
||||
@@ -2,13 +2,15 @@ import argparse
|
||||
import os
|
||||
import subprocess
|
||||
from datetime import datetime, timedelta
|
||||
from multiprocessing import Pool
|
||||
from pathlib import Path
|
||||
from multiprocessing import Pool
|
||||
|
||||
import pandas as pd
|
||||
from tqdm import tqdm
|
||||
|
||||
from utils.logger import logger
|
||||
|
||||
|
||||
MIN_SECONDS = int(os.getenv("MIN_SECONDS", 3))
|
||||
MAX_SECONDS = int(os.getenv("MAX_SECONDS", 10))
|
||||
|
||||
@@ -38,11 +40,10 @@ def clip_video_star(args):
|
||||
|
||||
def clip_video(video_path, timecode_list, output_folder, video_duration):
|
||||
"""Recursively clip the video within the range of [MIN_SECONDS, MAX_SECONDS],
|
||||
according to the timecode obtained from easyanimate/video_caption/cutscene_detect.py.
|
||||
according to the timecode obtained from cogvideox/video_caption/cutscene_detect.py.
|
||||
"""
|
||||
try:
|
||||
os.makedirs(output_folder, exist_ok=True)
|
||||
video_stem = Path(video_path).stem
|
||||
video_name = Path(video_path).stem
|
||||
|
||||
if len(timecode_list) == 0: # The video of a single scene.
|
||||
splitted_timecode_list = []
|
||||
@@ -58,7 +59,7 @@ def clip_video(video_path, timecode_list, output_folder, video_duration):
|
||||
splitted_index += 1
|
||||
continue
|
||||
splitted_timecode_list.append([cur_start.strftime("%H:%M:%S.%f")[:-3], cur_end.strftime("%H:%M:%S.%f")[:-3]])
|
||||
output_path = os.path.join(output_folder, video_stem + f"_{splitted_index}.mp4")
|
||||
output_path = os.path.join(output_folder, video_name + f"_{splitted_index}.mp4")
|
||||
if os.path.exists(output_path):
|
||||
logger.info(f"The clipped video {output_path} exists.")
|
||||
cur_start = cur_end
|
||||
@@ -78,7 +79,7 @@ def clip_video(video_path, timecode_list, output_folder, video_duration):
|
||||
start_time = datetime.strptime(timecode[0], "%H:%M:%S.%f")
|
||||
end_time = datetime.strptime(timecode[1], "%H:%M:%S.%f")
|
||||
video_duration = (end_time - start_time).total_seconds()
|
||||
output_path = os.path.join(output_folder, video_stem + f"_{i}.mp4")
|
||||
output_path = os.path.join(output_folder, video_name + f"_{i}.mp4")
|
||||
if os.path.exists(output_path):
|
||||
logger.info(f"The clipped video {output_path} exists.")
|
||||
continue
|
||||
@@ -94,7 +95,7 @@ def clip_video(video_path, timecode_list, output_folder, video_duration):
|
||||
if cur_video_duration < MIN_SECONDS:
|
||||
break
|
||||
splitted_timecode_list.append([cur_start.strftime("%H:%M:%S.%f")[:-3], cur_end.strftime("%H:%M:%S.%f")[:-3]])
|
||||
splitted_output_path = os.path.join(output_folder, video_stem + f"_{i}_{splitted_index}.mp4")
|
||||
splitted_output_path = os.path.join(output_folder, video_name + f"_{i}_{splitted_index}.mp4")
|
||||
if os.path.exists(splitted_output_path):
|
||||
logger.info(f"The clipped video {splitted_output_path} exists.")
|
||||
cur_start = cur_end
|
||||
@@ -146,23 +147,19 @@ if __name__ == "__main__":
|
||||
video_metadata_df = video_metadata_df[video_metadata_df["resolution"] >= args.resolution_threshold]
|
||||
logger.info(f"Filter {num_videos - len(video_metadata_df)} videos with resolution smaller than {args.resolution_threshold}.")
|
||||
video_path_list = video_metadata_df[args.video_path_column].to_list()
|
||||
video_id_list = [Path(video_path).stem for video_path in video_path_list]
|
||||
if len(video_id_list) != len(list(set(video_id_list))):
|
||||
logger.warning("Duplicate file names exist in the input video path list.")
|
||||
video_path_list = [os.path.join(args.video_folder, video_path) for video_path in video_path_list]
|
||||
video_timecode_list = video_metadata_df["timecode_list"].to_list()
|
||||
video_duration_list = video_metadata_df["duration"].to_list()
|
||||
|
||||
if args.video_folder == "":
|
||||
output_folder_list = [args.output_folder] * len(video_path_list)
|
||||
video_name_list = [Path(video_path).name for video_path in video_path_list]
|
||||
# We only check the unique video name with the absolute video path.
|
||||
if len(video_name_list) != len(set(video_name_list)):
|
||||
logger.error(f"The video path in {args.video_metadata_path} should has an unique video name.")
|
||||
else:
|
||||
output_folder_list = [os.path.join(args.output_folder, os.path.dirname(video_path)) for video_path in video_path_list]
|
||||
video_path_list = [os.path.join(args.video_folder, video_path) for video_path in video_path_list]
|
||||
|
||||
assert len(video_path_list) == len(video_timecode_list)
|
||||
os.makedirs(args.output_folder, exist_ok=True)
|
||||
args_list = [
|
||||
(video_path, timecode_list, output_folder, video_duration)
|
||||
for video_path, timecode_list, output_folder, video_duration in zip(
|
||||
video_path_list, video_timecode_list, output_folder_list, video_duration_list
|
||||
(video_path, timecode_list, args.output_folder, video_duration)
|
||||
for video_path, timecode_list, video_duration in zip(
|
||||
video_path_list, video_timecode_list, video_duration_list
|
||||
)
|
||||
]
|
||||
with Pool(args.n_jobs) as pool:
|
||||
@@ -0,0 +1,354 @@
|
||||
# Modified from https://github.com/mit-han-lab/llm-awq/blob/main/tinychat/vlm_demo_new.py.
|
||||
import argparse
|
||||
import os
|
||||
from pathlib import Path
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
import torch
|
||||
from accelerate import load_checkpoint_and_dispatch, PartialState
|
||||
from accelerate.utils import gather_object
|
||||
from decord import VideoReader
|
||||
from PIL import Image
|
||||
from natsort import natsorted
|
||||
from tqdm import tqdm
|
||||
from transformers import AutoConfig, AutoTokenizer
|
||||
|
||||
import tinychat.utils.constants
|
||||
# from tinychat.models.llava_llama import LlavaLlamaForCausalLM
|
||||
from tinychat.models.vila_llama import VilaLlamaForCausalLM
|
||||
from tinychat.stream_generators.llava_stream_gen import LlavaStreamGenerator
|
||||
from tinychat.utils.conversation_utils import gen_params
|
||||
from tinychat.utils.llava_image_processing import process_images
|
||||
from tinychat.utils.prompt_templates import (
|
||||
get_image_token,
|
||||
get_prompter,
|
||||
get_stop_token_ids,
|
||||
)
|
||||
from tinychat.utils.tune import (
|
||||
device_warmup,
|
||||
tune_llava_patch_embedding,
|
||||
)
|
||||
|
||||
from utils.filter import filter
|
||||
from utils.logger import logger
|
||||
|
||||
gen_params.seed = 1
|
||||
gen_params.temp = 1.0
|
||||
gen_params.top_p = 1.0
|
||||
|
||||
|
||||
def extract_uniform_frames(video_path: str, num_sampled_frames: int = 8):
|
||||
vr = VideoReader(video_path)
|
||||
sampled_frame_idx_list = np.linspace(0, len(vr), num_sampled_frames, endpoint=False, dtype=int)
|
||||
sampled_frame_list = []
|
||||
for idx in sampled_frame_idx_list:
|
||||
sampled_frame = Image.fromarray(vr[idx].asnumpy())
|
||||
sampled_frame_list.append(sampled_frame)
|
||||
|
||||
return sampled_frame_list
|
||||
|
||||
|
||||
def stream_output(output_stream):
|
||||
for outputs in output_stream:
|
||||
output_text = outputs["text"]
|
||||
output_text = output_text.strip().split(" ")
|
||||
# print(f"output_text: {output_text}.")
|
||||
return " ".join(output_text)
|
||||
|
||||
|
||||
def skip(*args, **kwargs):
|
||||
pass
|
||||
|
||||
|
||||
def parse_args():
|
||||
parser = argparse.ArgumentParser(description="Recaption videos with VILA1.5.")
|
||||
parser.add_argument(
|
||||
"--video_metadata_path",
|
||||
type=str,
|
||||
default=None,
|
||||
help="The path to the video dataset metadata (csv/jsonl).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--video_path_column",
|
||||
type=str,
|
||||
default="video_path",
|
||||
help="The column contains the video path (an absolute path or a relative path w.r.t the video_folder).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--caption_column",
|
||||
type=str,
|
||||
default="caption",
|
||||
help="The column contains the caption.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--video_folder", type=str, default="", help="The video folder."
|
||||
)
|
||||
parser.add_argument("--input_prompt", type=str, default="<video>\\n Elaborate on the visual and narrative elements of the video in detail.")
|
||||
parser.add_argument(
|
||||
"--model_type", type=str, default="LLaMa", help="type of the model"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_path", type=str, default="Efficient-Large-Model/Llama-3-VILA1.5-8b-AWQ"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--quant_path",
|
||||
type=str,
|
||||
default=None,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--precision", type=str, default="W4A16", help="compute precision"
|
||||
)
|
||||
parser.add_argument("--num_sampled_frames", type=int, default=8)
|
||||
parser.add_argument(
|
||||
"--saved_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="The save path to the output results (csv/jsonl).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--saved_freq",
|
||||
type=int,
|
||||
default=100,
|
||||
help="The frequency to save the output results.",
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--basic_metadata_path", type=str, default=None, help="The path to the basic metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_resolution", type=float, default=0, help="The resolution threshold.")
|
||||
parser.add_argument("--min_duration", type=float, default=-1, help="The minimum duration.")
|
||||
parser.add_argument("--max_duration", type=float, default=-1, help="The maximum duration.")
|
||||
parser.add_argument(
|
||||
"--asethetic_score_metadata_path", type=str, default=None, help="The path to the video quality metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_asethetic_score", type=float, default=4.0, help="The asethetic score threshold.")
|
||||
parser.add_argument(
|
||||
"--asethetic_score_siglip_metadata_path", type=str, default=None, help="The path to the video quality metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_asethetic_score_siglip", type=float, default=4.0, help="The asethetic score (SigLIP) threshold.")
|
||||
parser.add_argument(
|
||||
"--text_score_metadata_path", type=str, default=None, help="The path to the video text score metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_text_score", type=float, default=0.02, help="The text threshold.")
|
||||
parser.add_argument(
|
||||
"--motion_score_metadata_path", type=str, default=None, help="The path to the video motion score metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_motion_score", type=float, default=2, help="The motion threshold.")
|
||||
|
||||
args = parser.parse_args()
|
||||
return args
|
||||
|
||||
|
||||
def main(args):
|
||||
if args.video_metadata_path.endswith(".csv"):
|
||||
video_metadata_df = pd.read_csv(args.video_metadata_path)
|
||||
elif args.video_metadata_path.endswith(".jsonl"):
|
||||
video_metadata_df = pd.read_json(args.video_metadata_path, lines=True)
|
||||
else:
|
||||
raise ValueError("The video_metadata_path must end with .csv or .jsonl.")
|
||||
video_path_list = video_metadata_df[args.video_path_column].tolist()
|
||||
video_path_list = [os.path.basename(video_path) for video_path in video_path_list]
|
||||
|
||||
if not (args.saved_path.endswith(".csv") or args.saved_path.endswith(".jsonl")):
|
||||
raise ValueError("The saved_path must end with .csv or .jsonl.")
|
||||
|
||||
if os.path.exists(args.saved_path):
|
||||
if args.saved_path.endswith(".csv"):
|
||||
saved_metadata_df = pd.read_csv(args.saved_path)
|
||||
elif args.saved_path.endswith(".jsonl"):
|
||||
saved_metadata_df = pd.read_json(args.saved_path, lines=True)
|
||||
saved_video_path_list = saved_metadata_df[args.video_path_column].tolist()
|
||||
video_path_list = list(set(video_path_list).difference(set(saved_video_path_list)))
|
||||
logger.info(
|
||||
f"Resume from {args.saved_path}: {len(saved_video_path_list)} processed and {len(video_path_list)} to be processed."
|
||||
)
|
||||
|
||||
video_path_list = filter(
|
||||
video_path_list,
|
||||
basic_metadata_path=args.basic_metadata_path,
|
||||
min_resolution=args.min_resolution,
|
||||
min_duration=args.min_duration,
|
||||
max_duration=args.max_duration,
|
||||
asethetic_score_metadata_path=args.asethetic_score_metadata_path,
|
||||
min_asethetic_score=args.min_asethetic_score,
|
||||
asethetic_score_siglip_metadata_path=args.asethetic_score_siglip_metadata_path,
|
||||
min_asethetic_score_siglip=args.min_asethetic_score_siglip,
|
||||
text_score_metadata_path=args.text_score_metadata_path,
|
||||
min_text_score=args.min_text_score,
|
||||
motion_score_metadata_path=args.motion_score_metadata_path,
|
||||
min_motion_score=args.min_motion_score,
|
||||
)
|
||||
video_path_list = [os.path.join(args.video_folder, video_path) for video_path in video_path_list]
|
||||
# Sorting to guarantee the same result for each process.
|
||||
video_path_list = natsorted(video_path_list)
|
||||
|
||||
state = PartialState()
|
||||
|
||||
# Accelerate model initialization
|
||||
setattr(torch.nn.Linear, "reset_parameters", lambda self: None)
|
||||
setattr(torch.nn.LayerNorm, "reset_parameters", lambda self: None)
|
||||
torch.nn.init.kaiming_uniform_ = skip
|
||||
torch.nn.init.kaiming_normal_ = skip
|
||||
torch.nn.init.uniform_ = skip
|
||||
torch.nn.init.normal_ = skip
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(os.path.join(args.model_path, "llm"), use_fast=False)
|
||||
tinychat.utils.constants.LLAVA_DEFAULT_IMAGE_PATCH_TOKEN_IDX = (
|
||||
tokenizer.convert_tokens_to_ids(
|
||||
[tinychat.utils.constants.LLAVA_DEFAULT_IMAGE_PATCH_TOKEN]
|
||||
)[0]
|
||||
)
|
||||
config = AutoConfig.from_pretrained(args.model_path, trust_remote_code=True)
|
||||
model = VilaLlamaForCausalLM(config).half()
|
||||
tinychat.utils.constants.LLAVA_DEFAULT_IMAGE_PATCH_TOKEN_IDX = (
|
||||
tokenizer.convert_tokens_to_ids(
|
||||
[tinychat.utils.constants.LLAVA_DEFAULT_IMAGE_PATCH_TOKEN]
|
||||
)[0]
|
||||
)
|
||||
vision_tower = model.get_vision_tower()
|
||||
# if not vision_tower.is_loaded:
|
||||
# vision_tower.load_model()
|
||||
image_processor = vision_tower.image_processor
|
||||
# vision_tower = vision_tower.half()
|
||||
|
||||
if args.precision == "W16A16":
|
||||
pbar = tqdm(range(1))
|
||||
pbar.set_description("Loading checkpoint shards")
|
||||
for i in pbar:
|
||||
model.llm = load_checkpoint_and_dispatch(
|
||||
model.llm,
|
||||
os.path.join(args.model_path, "llm"),
|
||||
no_split_module_classes=[
|
||||
"OPTDecoderLayer",
|
||||
"LlamaDecoderLayer",
|
||||
"BloomBlock",
|
||||
"MPTBlock",
|
||||
"DecoderLayer",
|
||||
"CLIPEncoderLayer",
|
||||
],
|
||||
).to(state.device)
|
||||
model = model.to(state.device)
|
||||
|
||||
elif args.precision == "W4A16":
|
||||
from tinychat.utils.load_quant import load_awq_model
|
||||
# Auto load quant_path from the 3b/8b/13b/40b model.
|
||||
if args.quant_path is None:
|
||||
if "VILA1.5-3b-s2-AWQ" in args.model_path:
|
||||
args.quant_path = os.path.join(args.model_path, "llm/vila-1.5-3b-s2-w4-g128-awq-v2.pt")
|
||||
elif "VILA1.5-3b-AWQ" in args.model_path:
|
||||
args.quant_path = os.path.join(args.model_path, "llm/vila-1.5-3b-w4-g128-awq-v2.pt")
|
||||
elif "Llama-3-VILA1.5-8b-AWQ" in args.model_path:
|
||||
args.quant_path = os.path.join(args.model_path, "llm/llama-3-vila1.5-8b-w4-g128-awq-v2.pt")
|
||||
elif "VILA1.5-13b-AWQ" in args.model_path:
|
||||
args.quant_path = os.path.join(args.model_path, "llm/vila-1.5-13b-w4-g128-awq-v2.pt")
|
||||
elif "VILA1.5-40b-AWQ" in args.model_path:
|
||||
args.quant_path = os.path.join(args.model_path, "llm/vila-1.5-40b-w4-g128-awq-v2.pt")
|
||||
model.llm = load_awq_model(model.llm, args.quant_path, 4, 128, state.device)
|
||||
from tinychat.modules import (
|
||||
make_fused_mlp,
|
||||
make_fused_vision_attn,
|
||||
make_quant_attn,
|
||||
make_quant_norm,
|
||||
)
|
||||
|
||||
make_quant_attn(model.llm, state.device)
|
||||
make_quant_norm(model.llm)
|
||||
# make_fused_mlp(model)
|
||||
# make_fused_vision_attn(model,state.device)
|
||||
model = model.to(state.device)
|
||||
|
||||
else:
|
||||
raise NotImplementedError(f"Precision {args.precision} is not supported.")
|
||||
|
||||
device_warmup(state.device)
|
||||
tune_llava_patch_embedding(vision_tower, device=state.device)
|
||||
|
||||
stream_generator = LlavaStreamGenerator
|
||||
|
||||
model_prompter = get_prompter(
|
||||
args.model_type, args.model_path, False, False
|
||||
)
|
||||
stop_token_ids = get_stop_token_ids(args.model_type, args.model_path)
|
||||
|
||||
model.eval()
|
||||
|
||||
index = len(video_path_list) - len(video_path_list) % state.num_processes
|
||||
# Avoid the NCCL timeout in the final gather operation.
|
||||
logger.info(f"Drop {len(video_path_list) % state.num_processes} videos to ensure each process handles the same number of videos.")
|
||||
video_path_list = video_path_list[:index]
|
||||
logger.info(f"{len(video_path_list)} videos are to be processed.")
|
||||
|
||||
result_dict = {args.video_path_column: [], args.caption_column: []}
|
||||
with state.split_between_processes(video_path_list) as splitted_video_path_list:
|
||||
# TODO: Use VideoDataset.
|
||||
for i, video_path in enumerate(tqdm(splitted_video_path_list)):
|
||||
try:
|
||||
image_list = extract_uniform_frames(video_path, args.num_sampled_frames)
|
||||
image_num = len(image_list)
|
||||
# Similar operation in model_worker.py
|
||||
image_tensor = process_images(image_list, image_processor, model.config)
|
||||
if type(image_tensor) is list:
|
||||
image_tensor = [
|
||||
image.to(state.device, dtype=torch.float16) for image in image_tensor
|
||||
]
|
||||
else:
|
||||
image_tensor = image_tensor.to(state.device, dtype=torch.float16)
|
||||
|
||||
input_prompt = args.input_prompt
|
||||
# Insert image here
|
||||
image_token = get_image_token(model, args.model_path)
|
||||
image_token_holder = tinychat.utils.constants.LLAVA_DEFAULT_IM_TOKEN_PLACE_HOLDER
|
||||
im_token_count = input_prompt.count(image_token_holder)
|
||||
if im_token_count == 0:
|
||||
model_prompter.insert_prompt(image_token * image_num + input_prompt)
|
||||
else:
|
||||
assert im_token_count == image_num
|
||||
input_prompt = input_prompt.replace(image_token_holder, image_token)
|
||||
model_prompter.insert_prompt(input_prompt)
|
||||
output_stream = stream_generator(
|
||||
model,
|
||||
tokenizer,
|
||||
model_prompter.model_input,
|
||||
gen_params,
|
||||
device=state.device,
|
||||
stop_token_ids=stop_token_ids,
|
||||
image_tensor=image_tensor,
|
||||
)
|
||||
outputs = stream_output(output_stream)
|
||||
if len(outputs) != 0:
|
||||
result_dict[args.video_path_column].append(Path(video_path).name)
|
||||
result_dict[args.caption_column].append(outputs)
|
||||
|
||||
except Exception as e:
|
||||
logger.warning(f"VILA with {video_path} failed. Error is {e}.")
|
||||
|
||||
if i != 0 and i % args.saved_freq == 0:
|
||||
state.wait_for_everyone()
|
||||
gathered_result_dict = {k: gather_object(v) for k, v in result_dict.items()}
|
||||
if state.is_main_process and len(gathered_result_dict[args.video_path_column]) != 0:
|
||||
result_df = pd.DataFrame(gathered_result_dict)
|
||||
if args.saved_path.endswith(".csv"):
|
||||
header = False if os.path.exists(args.saved_path) else True
|
||||
result_df.to_csv(args.saved_path, header=header, index=False, mode="a")
|
||||
elif args.saved_path.endswith(".jsonl"):
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, mode="a", force_ascii=False)
|
||||
logger.info(f"Save result to {args.saved_path}.")
|
||||
for k in result_dict.keys():
|
||||
result_dict[k] = []
|
||||
|
||||
state.wait_for_everyone()
|
||||
gathered_result_dict = {k: gather_object(v) for k, v in result_dict.items()}
|
||||
if state.is_main_process and len(gathered_result_dict[args.video_path_column]) != 0:
|
||||
result_df = pd.DataFrame(gathered_result_dict)
|
||||
if args.saved_path.endswith(".csv"):
|
||||
header = False if os.path.exists(args.saved_path) else True
|
||||
result_df.to_csv(args.saved_path, header=header, index=False, mode="a")
|
||||
elif args.saved_path.endswith(".jsonl"):
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, mode="a", force_ascii=False)
|
||||
logger.info(f"Save result to {args.saved_path}.")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
args = parse_args()
|
||||
main(args)
|
||||
@@ -1,62 +1,65 @@
|
||||
# ComfyUI VideoX-Fun
|
||||
Easily use VideoX-Fun inside ComfyUI!
|
||||
# ComfyUI CogVideoX-Fun
|
||||
Easily use CogVideoX-Fun inside ComfyUI!
|
||||
|
||||
- [Installation](#1-installation)
|
||||
- [Node types](#node-types)
|
||||
- [Example workflows](#example-workflows)
|
||||
|
||||
## Installation
|
||||
### 1. ComfyUI Installation
|
||||
## 1. Installation
|
||||
|
||||
#### Option 1: Install via ComfyUI Manager
|
||||
|
||||
### Option 1: Install via ComfyUI Manager
|
||||
TBD
|
||||
|
||||
#### Option 2: Install manually
|
||||
The VideoX-Fun repository needs to be placed at `ComfyUI/custom_nodes/VideoX-Fun/`.
|
||||
### Option 2: Install manually
|
||||
The CogVideoX-Fun repository needs to be placed at `ComfyUI/custom_nodes/CogVideoX-Fun/`.
|
||||
|
||||
```
|
||||
cd ComfyUI/custom_nodes/
|
||||
|
||||
# Git clone the cogvideox_fun itself
|
||||
git clone https://github.com/aigc-apps/VideoX-Fun.git
|
||||
git clone https://github.com/aigc-apps/CogVideoX-Fun.git
|
||||
|
||||
# Git clone the video outout node
|
||||
git clone https://github.com/Kosinkadink/ComfyUI-VideoHelperSuite.git
|
||||
|
||||
# Git clone the KJ Nodes
|
||||
git clone https://github.com/kijai/ComfyUI-KJNodes.git
|
||||
|
||||
cd VideoX-Fun/
|
||||
cd CogVideoX-Fun/
|
||||
python install.py
|
||||
```
|
||||
|
||||
### 2. Download models
|
||||
#### i、Full loading
|
||||
Download full model into `ComfyUI/models/Fun_Models/`.
|
||||
### 2. Download models into `ComfyUI/models/CogVideoX-Fun/`
|
||||
|
||||
#### ii、Chunked loading
|
||||
Put the transformer model weights to the `ComfyUI/models/diffusion_models/`.
|
||||
Put the text encoer model weights to the `ComfyUI/models/text_encoders/`.
|
||||
Put the clip vision model weights to the `ComfyUI/models/clip_vision/`.
|
||||
Put the vae model weights to the `ComfyUI/models/vae/`.
|
||||
Put the tokenizer files to the `ComfyUI/models/Fun_Models/` (For example: `ComfyUI/models/Fun_Models/umt5-xxl`).
|
||||
| Name | Storage Space | Url | Hugging Face | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP.tar.gz | Before extraction:9.69 GB \/ After extraction: 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 144 frames at a rate of 24 frames per second. |
|
||||
|
||||
### 3. (Optional) Download preprocess weights into `ComfyUI/custom_nodes/Fun_Models/Third_Party/`.
|
||||
Except for the fun models' weights, if you want to use the control preprocess nodes, you can download the preprocess weights to `ComfyUI/custom_nodes/Fun_Models/Third_Party/`.
|
||||
## Node types
|
||||
- **LoadCogVideoX_Fun_Model**
|
||||
- Loads the CogVideoX-Fun model
|
||||
- **TextBox**
|
||||
- Write the prompt for CogVideoX-Fun model
|
||||
- **CogVideoX_Fun_I2VSampler**
|
||||
- CogVideoX-Fun Sampler for Image to Video
|
||||
- **CogVideoX_Fun_T2VSampler**
|
||||
- CogVideoX-Fun Sampler for Text to Video
|
||||
- **CogVideoX_Fun_V2VSampler**
|
||||
- CogVideoX-Fun Sampler for Video to Video
|
||||
|
||||
```
|
||||
remote_onnx_det = "https://huggingface.co/yzd-v/DWPose/resolve/main/yolox_l.onnx"
|
||||
remote_onnx_pose = "https://huggingface.co/yzd-v/DWPose/resolve/main/dw-ll_ucoco_384.onnx"
|
||||
remote_zoe= "https://huggingface.co/lllyasviel/Annotators/resolve/main/ZoeD_M12_N.pt"
|
||||
```
|
||||
## Example workflows
|
||||
|
||||
## Support models
|
||||
### Video to video generation
|
||||
Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/cogvideoxfunv1_workflow_v2v.json) of the json:
|
||||

|
||||
|
||||
- [CogVideox-Fun](cogvideox_fun/README.md)
|
||||
- [Qwen-Image](qwenimage/README.md)
|
||||
- [Wan2.1](wan2_1/README.md)
|
||||
- [Wan2.2](wan2_2/README.md)
|
||||
- [Wan2.1-Fun](wan2_1_fun/README.md)
|
||||
- [Wan2.2-Fun](wan2_2_fun/README.md)
|
||||
- [Wan2.2-VACE-Fun](wan2_2_fun/README.md)
|
||||
- [Z-Image](z_image/README.md)
|
||||
You can run the demo using following video:
|
||||
[demo video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/play_guitar.mp4)
|
||||
|
||||
### Image to video generation
|
||||
Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/cogvideoxfunv1_workflow_i2v.json) of the json:
|
||||

|
||||
|
||||
You can run the demo using following photo:
|
||||

|
||||
|
||||
### Text to video generation
|
||||
Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/cogvideoxfunv1_workflow_t2v.json) of the json:
|
||||

|
||||
@@ -1,46 +0,0 @@
|
||||
# This folder is modified from the https://github.com/Mikubill/sd-webui-controlnet
|
||||
# Openpose
|
||||
# Original from CMU https://github.com/CMU-Perceptual-Computing-Lab/openpose
|
||||
# 2nd Edited by https://github.com/Hzzone/pytorch-openpose
|
||||
# 3rd Edited by ControlNet
|
||||
# 4th Edited by ControlNet (added face and correct hands)
|
||||
|
||||
import os
|
||||
|
||||
os.environ["KMP_DUPLICATE_LIB_OK"]="TRUE"
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
from . import util
|
||||
from .wholebody import Wholebody
|
||||
|
||||
|
||||
def draw_pose(poses, H, W):
|
||||
canvas = np.zeros(shape=(H, W, 3), dtype=np.uint8)
|
||||
|
||||
for pose in poses:
|
||||
canvas = util.draw_bodypose(canvas, pose.body.keypoints)
|
||||
|
||||
canvas = util.draw_handpose(canvas, pose.left_hand)
|
||||
canvas = util.draw_handpose(canvas, pose.right_hand)
|
||||
|
||||
canvas = util.draw_facepose(canvas, pose.face)
|
||||
return canvas
|
||||
|
||||
|
||||
class DWposeDetector:
|
||||
def __init__(self, onnx_det, onnx_pose):
|
||||
self.pose_estimation = Wholebody(onnx_det, onnx_pose)
|
||||
|
||||
def __call__(self, oriImg):
|
||||
oriImg = oriImg.copy()
|
||||
H, W, C = oriImg.shape
|
||||
with torch.no_grad():
|
||||
keypoints_info = self.pose_estimation(oriImg)
|
||||
return draw_pose(
|
||||
Wholebody.format_result(keypoints_info),
|
||||
H,
|
||||
W,
|
||||
)
|
||||
|
||||
@@ -1,129 +0,0 @@
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
|
||||
def nms(boxes, scores, nms_thr):
|
||||
"""Single class NMS implemented in Numpy."""
|
||||
x1 = boxes[:, 0]
|
||||
y1 = boxes[:, 1]
|
||||
x2 = boxes[:, 2]
|
||||
y2 = boxes[:, 3]
|
||||
|
||||
areas = (x2 - x1 + 1) * (y2 - y1 + 1)
|
||||
order = scores.argsort()[::-1]
|
||||
|
||||
keep = []
|
||||
while order.size > 0:
|
||||
i = order[0]
|
||||
keep.append(i)
|
||||
xx1 = np.maximum(x1[i], x1[order[1:]])
|
||||
yy1 = np.maximum(y1[i], y1[order[1:]])
|
||||
xx2 = np.minimum(x2[i], x2[order[1:]])
|
||||
yy2 = np.minimum(y2[i], y2[order[1:]])
|
||||
|
||||
w = np.maximum(0.0, xx2 - xx1 + 1)
|
||||
h = np.maximum(0.0, yy2 - yy1 + 1)
|
||||
inter = w * h
|
||||
ovr = inter / (areas[i] + areas[order[1:]] - inter)
|
||||
|
||||
inds = np.where(ovr <= nms_thr)[0]
|
||||
order = order[inds + 1]
|
||||
|
||||
return keep
|
||||
|
||||
def multiclass_nms(boxes, scores, nms_thr, score_thr):
|
||||
"""Multiclass NMS implemented in Numpy. Class-aware version."""
|
||||
final_dets = []
|
||||
num_classes = scores.shape[1]
|
||||
for cls_ind in range(num_classes):
|
||||
cls_scores = scores[:, cls_ind]
|
||||
valid_score_mask = cls_scores > score_thr
|
||||
if valid_score_mask.sum() == 0:
|
||||
continue
|
||||
else:
|
||||
valid_scores = cls_scores[valid_score_mask]
|
||||
valid_boxes = boxes[valid_score_mask]
|
||||
keep = nms(valid_boxes, valid_scores, nms_thr)
|
||||
if len(keep) > 0:
|
||||
cls_inds = np.ones((len(keep), 1)) * cls_ind
|
||||
dets = np.concatenate(
|
||||
[valid_boxes[keep], valid_scores[keep, None], cls_inds], 1
|
||||
)
|
||||
final_dets.append(dets)
|
||||
if len(final_dets) == 0:
|
||||
return None
|
||||
return np.concatenate(final_dets, 0)
|
||||
|
||||
def demo_postprocess(outputs, img_size, p6=False):
|
||||
grids = []
|
||||
expanded_strides = []
|
||||
strides = [8, 16, 32] if not p6 else [8, 16, 32, 64]
|
||||
|
||||
hsizes = [img_size[0] // stride for stride in strides]
|
||||
wsizes = [img_size[1] // stride for stride in strides]
|
||||
|
||||
for hsize, wsize, stride in zip(hsizes, wsizes, strides):
|
||||
xv, yv = np.meshgrid(np.arange(wsize), np.arange(hsize))
|
||||
grid = np.stack((xv, yv), 2).reshape(1, -1, 2)
|
||||
grids.append(grid)
|
||||
shape = grid.shape[:2]
|
||||
expanded_strides.append(np.full((*shape, 1), stride))
|
||||
|
||||
grids = np.concatenate(grids, 1)
|
||||
expanded_strides = np.concatenate(expanded_strides, 1)
|
||||
outputs[..., :2] = (outputs[..., :2] + grids) * expanded_strides
|
||||
outputs[..., 2:4] = np.exp(outputs[..., 2:4]) * expanded_strides
|
||||
|
||||
return outputs
|
||||
|
||||
def preprocess(img, input_size, swap=(2, 0, 1)):
|
||||
if len(img.shape) == 3:
|
||||
padded_img = np.ones((input_size[0], input_size[1], 3), dtype=np.uint8) * 114
|
||||
else:
|
||||
padded_img = np.ones(input_size, dtype=np.uint8) * 114
|
||||
|
||||
r = min(input_size[0] / img.shape[0], input_size[1] / img.shape[1])
|
||||
resized_img = cv2.resize(
|
||||
img,
|
||||
(int(img.shape[1] * r), int(img.shape[0] * r)),
|
||||
interpolation=cv2.INTER_LINEAR,
|
||||
).astype(np.uint8)
|
||||
padded_img[: int(img.shape[0] * r), : int(img.shape[1] * r)] = resized_img
|
||||
|
||||
padded_img = padded_img.transpose(swap)
|
||||
padded_img = np.ascontiguousarray(padded_img, dtype=np.float32)
|
||||
return padded_img, r
|
||||
|
||||
def inference_detector(session, oriImg, detect_classes=[0]):
|
||||
input_shape = (640,640)
|
||||
img, ratio = preprocess(oriImg, input_shape)
|
||||
|
||||
input = img[None, :, :, :]
|
||||
if "InferenceSession" in type(session).__name__:
|
||||
input_name = session.get_inputs()[0].name
|
||||
output = session.run(None, {input_name: input})
|
||||
else:
|
||||
outNames = session.getUnconnectedOutLayersNames()
|
||||
session.setInput(input)
|
||||
output = session.forward(outNames)
|
||||
|
||||
predictions = demo_postprocess(output[0], input_shape)[0]
|
||||
|
||||
boxes = predictions[:, :4]
|
||||
scores = predictions[:, 4:5] * predictions[:, 5:]
|
||||
|
||||
boxes_xyxy = np.ones_like(boxes)
|
||||
boxes_xyxy[:, 0] = boxes[:, 0] - boxes[:, 2]/2.
|
||||
boxes_xyxy[:, 1] = boxes[:, 1] - boxes[:, 3]/2.
|
||||
boxes_xyxy[:, 2] = boxes[:, 0] + boxes[:, 2]/2.
|
||||
boxes_xyxy[:, 3] = boxes[:, 1] + boxes[:, 3]/2.
|
||||
boxes_xyxy /= ratio
|
||||
dets = multiclass_nms(boxes_xyxy, scores, nms_thr=0.45, score_thr=0.1)
|
||||
if dets is None:
|
||||
return None
|
||||
final_boxes, final_scores, final_cls_inds = dets[:, :4], dets[:, 4], dets[:, 5]
|
||||
isscore = final_scores>0.3
|
||||
iscat = np.isin(final_cls_inds, detect_classes)
|
||||
isbbox = [ i and j for (i, j) in zip(isscore, iscat)]
|
||||
final_boxes = final_boxes[isbbox]
|
||||
return final_boxes
|
||||
@@ -1,365 +0,0 @@
|
||||
from typing import List, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
|
||||
def preprocess(
|
||||
img: np.ndarray, out_bbox, input_size: Tuple[int, int] = (192, 256)
|
||||
) -> Tuple[np.ndarray, np.ndarray, np.ndarray]:
|
||||
"""Do preprocessing for DWPose model inference.
|
||||
|
||||
Args:
|
||||
img (np.ndarray): Input image in shape.
|
||||
input_size (tuple): Input image size in shape (w, h).
|
||||
|
||||
Returns:
|
||||
tuple:
|
||||
- resized_img (np.ndarray): Preprocessed image.
|
||||
- center (np.ndarray): Center of image.
|
||||
- scale (np.ndarray): Scale of image.
|
||||
"""
|
||||
# get shape of image
|
||||
img_shape = img.shape[:2]
|
||||
out_img, out_center, out_scale = [], [], []
|
||||
if len(out_bbox) == 0:
|
||||
out_bbox = [[0, 0, img_shape[1], img_shape[0]]]
|
||||
for i in range(len(out_bbox)):
|
||||
x0 = out_bbox[i][0]
|
||||
y0 = out_bbox[i][1]
|
||||
x1 = out_bbox[i][2]
|
||||
y1 = out_bbox[i][3]
|
||||
bbox = np.array([x0, y0, x1, y1])
|
||||
|
||||
# get center and scale
|
||||
center, scale = bbox_xyxy2cs(bbox, padding=1.25)
|
||||
|
||||
# do affine transformation
|
||||
resized_img, scale = top_down_affine(input_size, scale, center, img)
|
||||
|
||||
# normalize image
|
||||
mean = np.array([123.675, 116.28, 103.53])
|
||||
std = np.array([58.395, 57.12, 57.375])
|
||||
resized_img = (resized_img - mean) / std
|
||||
|
||||
out_img.append(resized_img)
|
||||
out_center.append(center)
|
||||
out_scale.append(scale)
|
||||
|
||||
return out_img, out_center, out_scale
|
||||
|
||||
|
||||
def inference(sess, img):
|
||||
"""Inference DWPose model.
|
||||
|
||||
Args:
|
||||
sess : ONNXRuntime session.
|
||||
img : Input image in shape.
|
||||
|
||||
Returns:
|
||||
outputs : Output of DWPose model.
|
||||
"""
|
||||
all_out = []
|
||||
# build input
|
||||
input = np.stack(img, axis=0).transpose(0, 3, 1, 2)
|
||||
input = input.astype(np.float32)
|
||||
if "InferenceSession" in type(sess).__name__:
|
||||
input_name = sess.get_inputs()[0].name
|
||||
all_outputs = sess.run(None, {input_name: input})
|
||||
for batch_idx in range(len(all_outputs[0])):
|
||||
outputs = [all_outputs[i][batch_idx:batch_idx+1,...] for i in range(len(all_outputs))]
|
||||
all_out.append(outputs)
|
||||
return all_out
|
||||
|
||||
for i in range(len(img)):
|
||||
|
||||
input = img[i].transpose(2, 0, 1)
|
||||
input = input[None, :, :, :]
|
||||
|
||||
outNames = sess.getUnconnectedOutLayersNames()
|
||||
sess.setInput(input)
|
||||
outputs = sess.forward(outNames)
|
||||
all_out.append(outputs)
|
||||
|
||||
return all_out
|
||||
|
||||
|
||||
def postprocess(outputs: List[np.ndarray],
|
||||
model_input_size: Tuple[int, int],
|
||||
center: Tuple[int, int],
|
||||
scale: Tuple[int, int],
|
||||
simcc_split_ratio: float = 2.0
|
||||
) -> Tuple[np.ndarray, np.ndarray]:
|
||||
"""Postprocess for DWPose model output.
|
||||
|
||||
Args:
|
||||
outputs (np.ndarray): Output of RTMPose model.
|
||||
model_input_size (tuple): RTMPose model Input image size.
|
||||
center (tuple): Center of bbox in shape (x, y).
|
||||
scale (tuple): Scale of bbox in shape (w, h).
|
||||
simcc_split_ratio (float): Split ratio of simcc.
|
||||
|
||||
Returns:
|
||||
tuple:
|
||||
- keypoints (np.ndarray): Rescaled keypoints.
|
||||
- scores (np.ndarray): Model predict scores.
|
||||
"""
|
||||
all_key = []
|
||||
all_score = []
|
||||
for i in range(len(outputs)):
|
||||
# use simcc to decode
|
||||
simcc_x, simcc_y = outputs[i]
|
||||
keypoints, scores = decode(simcc_x, simcc_y, simcc_split_ratio)
|
||||
|
||||
# rescale keypoints
|
||||
keypoints = keypoints / model_input_size * scale[i] + center[i] - scale[i] / 2
|
||||
all_key.append(keypoints[0])
|
||||
all_score.append(scores[0])
|
||||
|
||||
return np.array(all_key), np.array(all_score)
|
||||
|
||||
|
||||
def bbox_xyxy2cs(bbox: np.ndarray,
|
||||
padding: float = 1.) -> Tuple[np.ndarray, np.ndarray]:
|
||||
"""Transform the bbox format from (x,y,w,h) into (center, scale)
|
||||
|
||||
Args:
|
||||
bbox (ndarray): Bounding box(es) in shape (4,) or (n, 4), formatted
|
||||
as (left, top, right, bottom)
|
||||
padding (float): BBox padding factor that will be multilied to scale.
|
||||
Default: 1.0
|
||||
|
||||
Returns:
|
||||
tuple: A tuple containing center and scale.
|
||||
- np.ndarray[float32]: Center (x, y) of the bbox in shape (2,) or
|
||||
(n, 2)
|
||||
- np.ndarray[float32]: Scale (w, h) of the bbox in shape (2,) or
|
||||
(n, 2)
|
||||
"""
|
||||
# convert single bbox from (4, ) to (1, 4)
|
||||
dim = bbox.ndim
|
||||
if dim == 1:
|
||||
bbox = bbox[None, :]
|
||||
|
||||
# get bbox center and scale
|
||||
x1, y1, x2, y2 = np.hsplit(bbox, [1, 2, 3])
|
||||
center = np.hstack([x1 + x2, y1 + y2]) * 0.5
|
||||
scale = np.hstack([x2 - x1, y2 - y1]) * padding
|
||||
|
||||
if dim == 1:
|
||||
center = center[0]
|
||||
scale = scale[0]
|
||||
|
||||
return center, scale
|
||||
|
||||
|
||||
def _fix_aspect_ratio(bbox_scale: np.ndarray,
|
||||
aspect_ratio: float) -> np.ndarray:
|
||||
"""Extend the scale to match the given aspect ratio.
|
||||
|
||||
Args:
|
||||
scale (np.ndarray): The image scale (w, h) in shape (2, )
|
||||
aspect_ratio (float): The ratio of ``w/h``
|
||||
|
||||
Returns:
|
||||
np.ndarray: The reshaped image scale in (2, )
|
||||
"""
|
||||
w, h = np.hsplit(bbox_scale, [1])
|
||||
bbox_scale = np.where(w > h * aspect_ratio,
|
||||
np.hstack([w, w / aspect_ratio]),
|
||||
np.hstack([h * aspect_ratio, h]))
|
||||
return bbox_scale
|
||||
|
||||
|
||||
def _rotate_point(pt: np.ndarray, angle_rad: float) -> np.ndarray:
|
||||
"""Rotate a point by an angle.
|
||||
|
||||
Args:
|
||||
pt (np.ndarray): 2D point coordinates (x, y) in shape (2, )
|
||||
angle_rad (float): rotation angle in radian
|
||||
|
||||
Returns:
|
||||
np.ndarray: Rotated point in shape (2, )
|
||||
"""
|
||||
sn, cs = np.sin(angle_rad), np.cos(angle_rad)
|
||||
rot_mat = np.array([[cs, -sn], [sn, cs]])
|
||||
return rot_mat @ pt
|
||||
|
||||
|
||||
def _get_3rd_point(a: np.ndarray, b: np.ndarray) -> np.ndarray:
|
||||
"""To calculate the affine matrix, three pairs of points are required. This
|
||||
function is used to get the 3rd point, given 2D points a & b.
|
||||
|
||||
The 3rd point is defined by rotating vector `a - b` by 90 degrees
|
||||
anticlockwise, using b as the rotation center.
|
||||
|
||||
Args:
|
||||
a (np.ndarray): The 1st point (x,y) in shape (2, )
|
||||
b (np.ndarray): The 2nd point (x,y) in shape (2, )
|
||||
|
||||
Returns:
|
||||
np.ndarray: The 3rd point.
|
||||
"""
|
||||
direction = a - b
|
||||
c = b + np.r_[-direction[1], direction[0]]
|
||||
return c
|
||||
|
||||
|
||||
def get_warp_matrix(center: np.ndarray,
|
||||
scale: np.ndarray,
|
||||
rot: float,
|
||||
output_size: Tuple[int, int],
|
||||
shift: Tuple[float, float] = (0., 0.),
|
||||
inv: bool = False) -> np.ndarray:
|
||||
"""Calculate the affine transformation matrix that can warp the bbox area
|
||||
in the input image to the output size.
|
||||
|
||||
Args:
|
||||
center (np.ndarray[2, ]): Center of the bounding box (x, y).
|
||||
scale (np.ndarray[2, ]): Scale of the bounding box
|
||||
wrt [width, height].
|
||||
rot (float): Rotation angle (degree).
|
||||
output_size (np.ndarray[2, ] | list(2,)): Size of the
|
||||
destination heatmaps.
|
||||
shift (0-100%): Shift translation ratio wrt the width/height.
|
||||
Default (0., 0.).
|
||||
inv (bool): Option to inverse the affine transform direction.
|
||||
(inv=False: src->dst or inv=True: dst->src)
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 2x3 transformation matrix
|
||||
"""
|
||||
shift = np.array(shift)
|
||||
src_w = scale[0]
|
||||
dst_w = output_size[0]
|
||||
dst_h = output_size[1]
|
||||
|
||||
# compute transformation matrix
|
||||
rot_rad = np.deg2rad(rot)
|
||||
src_dir = _rotate_point(np.array([0., src_w * -0.5]), rot_rad)
|
||||
dst_dir = np.array([0., dst_w * -0.5])
|
||||
|
||||
# get four corners of the src rectangle in the original image
|
||||
src = np.zeros((3, 2), dtype=np.float32)
|
||||
src[0, :] = center + scale * shift
|
||||
src[1, :] = center + src_dir + scale * shift
|
||||
src[2, :] = _get_3rd_point(src[0, :], src[1, :])
|
||||
|
||||
# get four corners of the dst rectangle in the input image
|
||||
dst = np.zeros((3, 2), dtype=np.float32)
|
||||
dst[0, :] = [dst_w * 0.5, dst_h * 0.5]
|
||||
dst[1, :] = np.array([dst_w * 0.5, dst_h * 0.5]) + dst_dir
|
||||
dst[2, :] = _get_3rd_point(dst[0, :], dst[1, :])
|
||||
|
||||
if inv:
|
||||
warp_mat = cv2.getAffineTransform(np.float32(dst), np.float32(src))
|
||||
else:
|
||||
warp_mat = cv2.getAffineTransform(np.float32(src), np.float32(dst))
|
||||
|
||||
return warp_mat
|
||||
|
||||
|
||||
def top_down_affine(input_size: dict, bbox_scale: dict, bbox_center: dict,
|
||||
img: np.ndarray) -> Tuple[np.ndarray, np.ndarray]:
|
||||
"""Get the bbox image as the model input by affine transform.
|
||||
|
||||
Args:
|
||||
input_size (dict): The input size of the model.
|
||||
bbox_scale (dict): The bbox scale of the img.
|
||||
bbox_center (dict): The bbox center of the img.
|
||||
img (np.ndarray): The original image.
|
||||
|
||||
Returns:
|
||||
tuple: A tuple containing center and scale.
|
||||
- np.ndarray[float32]: img after affine transform.
|
||||
- np.ndarray[float32]: bbox scale after affine transform.
|
||||
"""
|
||||
w, h = input_size
|
||||
warp_size = (int(w), int(h))
|
||||
|
||||
# reshape bbox to fixed aspect ratio
|
||||
bbox_scale = _fix_aspect_ratio(bbox_scale, aspect_ratio=w / h)
|
||||
|
||||
# get the affine matrix
|
||||
center = bbox_center
|
||||
scale = bbox_scale
|
||||
rot = 0
|
||||
warp_mat = get_warp_matrix(center, scale, rot, output_size=(w, h))
|
||||
|
||||
# do affine transform
|
||||
img = cv2.warpAffine(img, warp_mat, warp_size, flags=cv2.INTER_LINEAR)
|
||||
|
||||
return img, bbox_scale
|
||||
|
||||
|
||||
def get_simcc_maximum(simcc_x: np.ndarray,
|
||||
simcc_y: np.ndarray) -> Tuple[np.ndarray, np.ndarray]:
|
||||
"""Get maximum response location and value from simcc representations.
|
||||
|
||||
Note:
|
||||
instance number: N
|
||||
num_keypoints: K
|
||||
heatmap height: H
|
||||
heatmap width: W
|
||||
|
||||
Args:
|
||||
simcc_x (np.ndarray): x-axis SimCC in shape (K, Wx) or (N, K, Wx)
|
||||
simcc_y (np.ndarray): y-axis SimCC in shape (K, Wy) or (N, K, Wy)
|
||||
|
||||
Returns:
|
||||
tuple:
|
||||
- locs (np.ndarray): locations of maximum heatmap responses in shape
|
||||
(K, 2) or (N, K, 2)
|
||||
- vals (np.ndarray): values of maximum heatmap responses in shape
|
||||
(K,) or (N, K)
|
||||
"""
|
||||
N, K, Wx = simcc_x.shape
|
||||
simcc_x = simcc_x.reshape(N * K, -1)
|
||||
simcc_y = simcc_y.reshape(N * K, -1)
|
||||
|
||||
# get maximum value locations
|
||||
x_locs = np.argmax(simcc_x, axis=1)
|
||||
y_locs = np.argmax(simcc_y, axis=1)
|
||||
locs = np.stack((x_locs, y_locs), axis=-1).astype(np.float32)
|
||||
max_val_x = np.amax(simcc_x, axis=1)
|
||||
max_val_y = np.amax(simcc_y, axis=1)
|
||||
|
||||
# get maximum value across x and y axis
|
||||
mask = max_val_x > max_val_y
|
||||
max_val_x[mask] = max_val_y[mask]
|
||||
vals = max_val_x
|
||||
locs[vals <= 0.] = -1
|
||||
|
||||
# reshape
|
||||
locs = locs.reshape(N, K, 2)
|
||||
vals = vals.reshape(N, K)
|
||||
|
||||
return locs, vals
|
||||
|
||||
|
||||
def decode(simcc_x: np.ndarray, simcc_y: np.ndarray,
|
||||
simcc_split_ratio) -> Tuple[np.ndarray, np.ndarray]:
|
||||
"""Modulate simcc distribution with Gaussian.
|
||||
|
||||
Args:
|
||||
simcc_x (np.ndarray[K, Wx]): model predicted simcc in x.
|
||||
simcc_y (np.ndarray[K, Wy]): model predicted simcc in y.
|
||||
simcc_split_ratio (int): The split ratio of simcc.
|
||||
|
||||
Returns:
|
||||
tuple: A tuple containing center and scale.
|
||||
- np.ndarray[float32]: keypoints in shape (K, 2) or (n, K, 2)
|
||||
- np.ndarray[float32]: scores in shape (K,) or (n, K)
|
||||
"""
|
||||
keypoints, scores = get_simcc_maximum(simcc_x, simcc_y)
|
||||
keypoints /= simcc_split_ratio
|
||||
|
||||
return keypoints, scores
|
||||
|
||||
|
||||
def inference_pose(session, out_bbox, oriImg, model_input_size: Tuple[int, int]= (288, 384) ):
|
||||
resized_img, center, scale = preprocess(oriImg, out_bbox, model_input_size)
|
||||
outputs = inference(session, resized_img)
|
||||
keypoints, scores = postprocess(outputs, model_input_size, center, scale)
|
||||
|
||||
return keypoints, scores
|
||||
@@ -1,360 +0,0 @@
|
||||
import math
|
||||
|
||||
import cv2
|
||||
import matplotlib
|
||||
import numpy as np
|
||||
|
||||
eps = 0.01
|
||||
|
||||
def smart_resize(x, s):
|
||||
Ht, Wt = s
|
||||
if x.ndim == 2:
|
||||
Ho, Wo = x.shape
|
||||
Co = 1
|
||||
else:
|
||||
Ho, Wo, Co = x.shape
|
||||
if Co == 3 or Co == 1:
|
||||
k = float(Ht + Wt) / float(Ho + Wo)
|
||||
return cv2.resize(x, (int(Wt), int(Ht)), interpolation=cv2.INTER_AREA if k < 1 else cv2.INTER_LANCZOS4)
|
||||
else:
|
||||
return np.stack([smart_resize(x[:, :, i], s) for i in range(Co)], axis=2)
|
||||
|
||||
def smart_resize_k(x, fx, fy):
|
||||
if x.ndim == 2:
|
||||
Ho, Wo = x.shape
|
||||
Co = 1
|
||||
else:
|
||||
Ho, Wo, Co = x.shape
|
||||
Ht, Wt = Ho * fy, Wo * fx
|
||||
if Co == 3 or Co == 1:
|
||||
k = float(Ht + Wt) / float(Ho + Wo)
|
||||
return cv2.resize(x, (int(Wt), int(Ht)), interpolation=cv2.INTER_AREA if k < 1 else cv2.INTER_LANCZOS4)
|
||||
else:
|
||||
return np.stack([smart_resize_k(x[:, :, i], fx, fy) for i in range(Co)], axis=2)
|
||||
|
||||
def padRightDownCorner(img, stride, padValue):
|
||||
h = img.shape[0]
|
||||
w = img.shape[1]
|
||||
|
||||
pad = 4 * [None]
|
||||
pad[0] = 0 # up
|
||||
pad[1] = 0 # left
|
||||
pad[2] = 0 if (h % stride == 0) else stride - (h % stride) # down
|
||||
pad[3] = 0 if (w % stride == 0) else stride - (w % stride) # right
|
||||
|
||||
img_padded = img
|
||||
pad_up = np.tile(img_padded[0:1, :, :]*0 + padValue, (pad[0], 1, 1))
|
||||
img_padded = np.concatenate((pad_up, img_padded), axis=0)
|
||||
pad_left = np.tile(img_padded[:, 0:1, :]*0 + padValue, (1, pad[1], 1))
|
||||
img_padded = np.concatenate((pad_left, img_padded), axis=1)
|
||||
pad_down = np.tile(img_padded[-2:-1, :, :]*0 + padValue, (pad[2], 1, 1))
|
||||
img_padded = np.concatenate((img_padded, pad_down), axis=0)
|
||||
pad_right = np.tile(img_padded[:, -2:-1, :]*0 + padValue, (1, pad[3], 1))
|
||||
img_padded = np.concatenate((img_padded, pad_right), axis=1)
|
||||
|
||||
return img_padded, pad
|
||||
|
||||
def transfer(model, model_weights):
|
||||
transfered_model_weights = {}
|
||||
for weights_name in model.state_dict().keys():
|
||||
transfered_model_weights[weights_name] = model_weights['.'.join(weights_name.split('.')[1:])]
|
||||
return transfered_model_weights
|
||||
|
||||
def is_normalized(keypoints) -> bool:
|
||||
point_normalized = [
|
||||
0 <= abs(k.x) <= 1 and 0 <= abs(k.y) <= 1
|
||||
for k in keypoints
|
||||
if k is not None
|
||||
]
|
||||
if not point_normalized:
|
||||
return False
|
||||
return all(point_normalized)
|
||||
|
||||
def draw_bodypose(canvas: np.ndarray, keypoints) -> np.ndarray:
|
||||
"""
|
||||
Draw keypoints and limbs representing body pose on a given canvas.
|
||||
|
||||
Args:
|
||||
canvas (np.ndarray): A 3D numpy array representing the canvas (image) on which to draw the body pose.
|
||||
keypoints (List[Keypoint]): A list of Keypoint objects representing the body keypoints to be drawn.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 3D numpy array representing the modified canvas with the drawn body pose.
|
||||
|
||||
Note:
|
||||
The function expects the x and y coordinates of the keypoints to be normalized between 0 and 1.
|
||||
"""
|
||||
if not is_normalized(keypoints):
|
||||
H, W = 1.0, 1.0
|
||||
else:
|
||||
H, W, _ = canvas.shape
|
||||
|
||||
stickwidth = 4
|
||||
|
||||
limbSeq = [
|
||||
[2, 3], [2, 6], [3, 4], [4, 5],
|
||||
[6, 7], [7, 8], [2, 9], [9, 10],
|
||||
[10, 11], [2, 12], [12, 13], [13, 14],
|
||||
[2, 1], [1, 15], [15, 17], [1, 16],
|
||||
[16, 18],
|
||||
]
|
||||
|
||||
colors = [[255, 0, 0], [255, 85, 0], [255, 170, 0], [255, 255, 0], [170, 255, 0], [85, 255, 0], [0, 255, 0], \
|
||||
[0, 255, 85], [0, 255, 170], [0, 255, 255], [0, 170, 255], [0, 85, 255], [0, 0, 255], [85, 0, 255], \
|
||||
[170, 0, 255], [255, 0, 255], [255, 0, 170], [255, 0, 85]]
|
||||
|
||||
for (k1_index, k2_index), color in zip(limbSeq, colors):
|
||||
keypoint1 = keypoints[k1_index - 1]
|
||||
keypoint2 = keypoints[k2_index - 1]
|
||||
|
||||
if keypoint1 is None or keypoint2 is None:
|
||||
continue
|
||||
|
||||
Y = np.array([keypoint1.x, keypoint2.x]) * float(W)
|
||||
X = np.array([keypoint1.y, keypoint2.y]) * float(H)
|
||||
mX = np.mean(X)
|
||||
mY = np.mean(Y)
|
||||
length = ((X[0] - X[1]) ** 2 + (Y[0] - Y[1]) ** 2) ** 0.5
|
||||
angle = math.degrees(math.atan2(X[0] - X[1], Y[0] - Y[1]))
|
||||
polygon = cv2.ellipse2Poly((int(mY), int(mX)), (int(length / 2), stickwidth), int(angle), 0, 360, 1)
|
||||
cv2.fillConvexPoly(canvas, polygon, [int(float(c) * 0.6) for c in color])
|
||||
|
||||
for keypoint, color in zip(keypoints, colors):
|
||||
if keypoint is None:
|
||||
continue
|
||||
|
||||
x, y = keypoint.x, keypoint.y
|
||||
x = int(x * W)
|
||||
y = int(y * H)
|
||||
cv2.circle(canvas, (int(x), int(y)), 4, color, thickness=-1)
|
||||
|
||||
return canvas
|
||||
|
||||
def draw_handpose(canvas: np.ndarray, keypoints) -> np.ndarray:
|
||||
"""
|
||||
Draw keypoints and connections representing hand pose on a given canvas.
|
||||
|
||||
Args:
|
||||
canvas (np.ndarray): A 3D numpy array representing the canvas (image) on which to draw the hand pose.
|
||||
keypoints (List[Keypoint]| None): A list of Keypoint objects representing the hand keypoints to be drawn
|
||||
or None if no keypoints are present.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 3D numpy array representing the modified canvas with the drawn hand pose.
|
||||
|
||||
Note:
|
||||
The function expects the x and y coordinates of the keypoints to be normalized between 0 and 1.
|
||||
"""
|
||||
if not keypoints:
|
||||
return canvas
|
||||
|
||||
if not is_normalized(keypoints):
|
||||
H, W = 1.0, 1.0
|
||||
else:
|
||||
H, W, _ = canvas.shape
|
||||
|
||||
edges = [[0, 1], [1, 2], [2, 3], [3, 4], [0, 5], [5, 6], [6, 7], [7, 8], [0, 9], [9, 10], \
|
||||
[10, 11], [11, 12], [0, 13], [13, 14], [14, 15], [15, 16], [0, 17], [17, 18], [18, 19], [19, 20]]
|
||||
|
||||
for ie, (e1, e2) in enumerate(edges):
|
||||
k1 = keypoints[e1]
|
||||
k2 = keypoints[e2]
|
||||
if k1 is None or k2 is None:
|
||||
continue
|
||||
|
||||
x1 = int(k1.x * W)
|
||||
y1 = int(k1.y * H)
|
||||
x2 = int(k2.x * W)
|
||||
y2 = int(k2.y * H)
|
||||
if x1 > eps and y1 > eps and x2 > eps and y2 > eps:
|
||||
cv2.line(canvas, (x1, y1), (x2, y2), matplotlib.colors.hsv_to_rgb([ie / float(len(edges)), 1.0, 1.0]) * 255, thickness=2)
|
||||
|
||||
for keypoint in keypoints:
|
||||
if keypoint is None:
|
||||
continue
|
||||
|
||||
x, y = keypoint.x, keypoint.y
|
||||
x = int(x * W)
|
||||
y = int(y * H)
|
||||
if x > eps and y > eps:
|
||||
cv2.circle(canvas, (x, y), 4, (0, 0, 255), thickness=-1)
|
||||
return canvas
|
||||
|
||||
|
||||
def draw_facepose(canvas: np.ndarray, keypoints) -> np.ndarray:
|
||||
"""
|
||||
Draw keypoints representing face pose on a given canvas.
|
||||
|
||||
Args:
|
||||
canvas (np.ndarray): A 3D numpy array representing the canvas (image) on which to draw the face pose.
|
||||
keypoints (List[Keypoint]| None): A list of Keypoint objects representing the face keypoints to be drawn
|
||||
or None if no keypoints are present.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 3D numpy array representing the modified canvas with the drawn face pose.
|
||||
|
||||
Note:
|
||||
The function expects the x and y coordinates of the keypoints to be normalized between 0 and 1.
|
||||
"""
|
||||
if not keypoints:
|
||||
return canvas
|
||||
|
||||
if not is_normalized(keypoints):
|
||||
H, W = 1.0, 1.0
|
||||
else:
|
||||
H, W, _ = canvas.shape
|
||||
|
||||
for keypoint in keypoints:
|
||||
if keypoint is None:
|
||||
continue
|
||||
|
||||
x, y = keypoint.x, keypoint.y
|
||||
x = int(x * W)
|
||||
y = int(y * H)
|
||||
if x > eps and y > eps:
|
||||
cv2.circle(canvas, (x, y), 3, (255, 255, 255), thickness=-1)
|
||||
return canvas
|
||||
|
||||
# detect hand according to body pose keypoints
|
||||
# please refer to https://github.com/CMU-Perceptual-Computing-Lab/openpose/blob/master/src/openpose/hand/handDetector.cpp
|
||||
def handDetect(candidate, subset, oriImg):
|
||||
# right hand: wrist 4, elbow 3, shoulder 2
|
||||
# left hand: wrist 7, elbow 6, shoulder 5
|
||||
ratioWristElbow = 0.33
|
||||
detect_result = []
|
||||
image_height, image_width = oriImg.shape[0:2]
|
||||
for person in subset.astype(int):
|
||||
# if any of three not detected
|
||||
has_left = np.sum(person[[5, 6, 7]] == -1) == 0
|
||||
has_right = np.sum(person[[2, 3, 4]] == -1) == 0
|
||||
if not (has_left or has_right):
|
||||
continue
|
||||
hands = []
|
||||
#left hand
|
||||
if has_left:
|
||||
left_shoulder_index, left_elbow_index, left_wrist_index = person[[5, 6, 7]]
|
||||
x1, y1 = candidate[left_shoulder_index][:2]
|
||||
x2, y2 = candidate[left_elbow_index][:2]
|
||||
x3, y3 = candidate[left_wrist_index][:2]
|
||||
hands.append([x1, y1, x2, y2, x3, y3, True])
|
||||
# right hand
|
||||
if has_right:
|
||||
right_shoulder_index, right_elbow_index, right_wrist_index = person[[2, 3, 4]]
|
||||
x1, y1 = candidate[right_shoulder_index][:2]
|
||||
x2, y2 = candidate[right_elbow_index][:2]
|
||||
x3, y3 = candidate[right_wrist_index][:2]
|
||||
hands.append([x1, y1, x2, y2, x3, y3, False])
|
||||
|
||||
for x1, y1, x2, y2, x3, y3, is_left in hands:
|
||||
# pos_hand = pos_wrist + ratio * (pos_wrist - pos_elbox) = (1 + ratio) * pos_wrist - ratio * pos_elbox
|
||||
# handRectangle.x = posePtr[wrist*3] + ratioWristElbow * (posePtr[wrist*3] - posePtr[elbow*3]);
|
||||
# handRectangle.y = posePtr[wrist*3+1] + ratioWristElbow * (posePtr[wrist*3+1] - posePtr[elbow*3+1]);
|
||||
# const auto distanceWristElbow = getDistance(poseKeypoints, person, wrist, elbow);
|
||||
# const auto distanceElbowShoulder = getDistance(poseKeypoints, person, elbow, shoulder);
|
||||
# handRectangle.width = 1.5f * fastMax(distanceWristElbow, 0.9f * distanceElbowShoulder);
|
||||
x = x3 + ratioWristElbow * (x3 - x2)
|
||||
y = y3 + ratioWristElbow * (y3 - y2)
|
||||
distanceWristElbow = math.sqrt((x3 - x2) ** 2 + (y3 - y2) ** 2)
|
||||
distanceElbowShoulder = math.sqrt((x2 - x1) ** 2 + (y2 - y1) ** 2)
|
||||
width = 1.5 * max(distanceWristElbow, 0.9 * distanceElbowShoulder)
|
||||
# x-y refers to the center --> offset to topLeft point
|
||||
# handRectangle.x -= handRectangle.width / 2.f;
|
||||
# handRectangle.y -= handRectangle.height / 2.f;
|
||||
x -= width / 2
|
||||
y -= width / 2 # width = height
|
||||
# overflow the image
|
||||
if x < 0: x = 0
|
||||
if y < 0: y = 0
|
||||
width1 = width
|
||||
width2 = width
|
||||
if x + width > image_width: width1 = image_width - x
|
||||
if y + width > image_height: width2 = image_height - y
|
||||
width = min(width1, width2)
|
||||
# the max hand box value is 20 pixels
|
||||
if width >= 20:
|
||||
detect_result.append([int(x), int(y), int(width), is_left])
|
||||
|
||||
'''
|
||||
return value: [[x, y, w, True if left hand else False]].
|
||||
width=height since the network require squared input.
|
||||
x, y is the coordinate of top left
|
||||
'''
|
||||
return detect_result
|
||||
|
||||
# Written by Lvmin
|
||||
def faceDetect(candidate, subset, oriImg):
|
||||
# left right eye ear 14 15 16 17
|
||||
detect_result = []
|
||||
image_height, image_width = oriImg.shape[0:2]
|
||||
for person in subset.astype(int):
|
||||
has_head = person[0] > -1
|
||||
if not has_head:
|
||||
continue
|
||||
|
||||
has_left_eye = person[14] > -1
|
||||
has_right_eye = person[15] > -1
|
||||
has_left_ear = person[16] > -1
|
||||
has_right_ear = person[17] > -1
|
||||
|
||||
if not (has_left_eye or has_right_eye or has_left_ear or has_right_ear):
|
||||
continue
|
||||
|
||||
head, left_eye, right_eye, left_ear, right_ear = person[[0, 14, 15, 16, 17]]
|
||||
|
||||
width = 0.0
|
||||
x0, y0 = candidate[head][:2]
|
||||
|
||||
if has_left_eye:
|
||||
x1, y1 = candidate[left_eye][:2]
|
||||
d = max(abs(x0 - x1), abs(y0 - y1))
|
||||
width = max(width, d * 3.0)
|
||||
|
||||
if has_right_eye:
|
||||
x1, y1 = candidate[right_eye][:2]
|
||||
d = max(abs(x0 - x1), abs(y0 - y1))
|
||||
width = max(width, d * 3.0)
|
||||
|
||||
if has_left_ear:
|
||||
x1, y1 = candidate[left_ear][:2]
|
||||
d = max(abs(x0 - x1), abs(y0 - y1))
|
||||
width = max(width, d * 1.5)
|
||||
|
||||
if has_right_ear:
|
||||
x1, y1 = candidate[right_ear][:2]
|
||||
d = max(abs(x0 - x1), abs(y0 - y1))
|
||||
width = max(width, d * 1.5)
|
||||
|
||||
x, y = x0, y0
|
||||
|
||||
x -= width
|
||||
y -= width
|
||||
|
||||
if x < 0:
|
||||
x = 0
|
||||
|
||||
if y < 0:
|
||||
y = 0
|
||||
|
||||
width1 = width * 2
|
||||
width2 = width * 2
|
||||
|
||||
if x + width > image_width:
|
||||
width1 = image_width - x
|
||||
|
||||
if y + width > image_height:
|
||||
width2 = image_height - y
|
||||
|
||||
width = min(width1, width2)
|
||||
|
||||
if width >= 20:
|
||||
detect_result.append([int(x), int(y), int(width)])
|
||||
|
||||
return detect_result
|
||||
|
||||
# get max index of 2d array
|
||||
def npmax(array):
|
||||
arrayindex = array.argmax(1)
|
||||
arrayvalue = array.max(1)
|
||||
i = arrayvalue.argmax()
|
||||
j = arrayindex[i]
|
||||
return i, j
|
||||
@@ -1,130 +0,0 @@
|
||||
from typing import List, NamedTuple, Optional, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import onnxruntime as ort
|
||||
|
||||
from .onnxdet import inference_detector
|
||||
from .onnxpose import inference_pose
|
||||
|
||||
|
||||
class Keypoint(NamedTuple):
|
||||
x: float
|
||||
y: float
|
||||
score: float = 1.0
|
||||
id: int = -1
|
||||
|
||||
|
||||
class BodyResult(NamedTuple):
|
||||
# Note: Using `Optional` instead of `|` operator as the ladder is a Python
|
||||
# 3.10 feature.
|
||||
# Annotator code should be Python 3.8 Compatible, as controlnet repo uses
|
||||
# Python 3.8 environment.
|
||||
# https://github.com/lllyasviel/ControlNet/blob/d3284fcd0972c510635a4f5abe2eeb71dc0de524/environment.yaml#L6
|
||||
keypoints: List[Optional[Keypoint]]
|
||||
total_score: float = 0.0
|
||||
total_parts: int = 0
|
||||
|
||||
|
||||
HandResult = List[Keypoint]
|
||||
FaceResult = List[Keypoint]
|
||||
AnimalPoseResult = List[Keypoint]
|
||||
|
||||
|
||||
class HumanPoseResult(NamedTuple):
|
||||
body: BodyResult
|
||||
left_hand: Optional[HandResult]
|
||||
right_hand: Optional[HandResult]
|
||||
face: Optional[FaceResult]
|
||||
|
||||
|
||||
class Wholebody:
|
||||
def __init__(self, onnx_det: str, onnx_pose: str):
|
||||
# Always loads to CPU to avoid building OpenCV.
|
||||
device = 'cpu'
|
||||
backend = cv2.dnn.DNN_BACKEND_OPENCV if device == 'cpu' else cv2.dnn.DNN_BACKEND_CUDA
|
||||
# You need to manually build OpenCV through cmake to work with your GPU.
|
||||
providers = cv2.dnn.DNN_TARGET_CPU if device == 'cpu' else cv2.dnn.DNN_TARGET_CUDA
|
||||
|
||||
self.session_det = cv2.dnn.readNetFromONNX(onnx_det)
|
||||
self.session_det.setPreferableBackend(backend)
|
||||
self.session_det.setPreferableTarget(providers)
|
||||
|
||||
self.session_pose = cv2.dnn.readNetFromONNX(onnx_pose)
|
||||
self.session_pose.setPreferableBackend(backend)
|
||||
self.session_pose.setPreferableTarget(providers)
|
||||
|
||||
def __call__(self, oriImg):
|
||||
det_result = inference_detector(self.session_det, oriImg)
|
||||
if det_result is None:
|
||||
return None
|
||||
|
||||
keypoints, scores = inference_pose(self.session_pose, det_result, oriImg)
|
||||
|
||||
keypoints_info = np.concatenate(
|
||||
(keypoints, scores[..., None]), axis=-1)
|
||||
# compute neck joint
|
||||
neck = np.mean(keypoints_info[:, [5, 6]], axis=1)
|
||||
# neck score when visualizing pred
|
||||
neck[:, 2:4] = np.logical_and(
|
||||
keypoints_info[:, 5, 2:4] > 0.3,
|
||||
keypoints_info[:, 6, 2:4] > 0.3).astype(int)
|
||||
new_keypoints_info = np.insert(
|
||||
keypoints_info, 17, neck, axis=1)
|
||||
mmpose_idx = [
|
||||
17, 6, 8, 10, 7, 9, 12, 14, 16, 13, 15, 2, 1, 4, 3
|
||||
]
|
||||
openpose_idx = [
|
||||
1, 2, 3, 4, 6, 7, 8, 9, 10, 12, 13, 14, 15, 16, 17
|
||||
]
|
||||
new_keypoints_info[:, openpose_idx] = \
|
||||
new_keypoints_info[:, mmpose_idx]
|
||||
keypoints_info = new_keypoints_info
|
||||
|
||||
return keypoints_info
|
||||
|
||||
@staticmethod
|
||||
def format_result(keypoints_info: Optional[np.ndarray]) -> List[HumanPoseResult]:
|
||||
def format_keypoint_part(
|
||||
part: np.ndarray,
|
||||
) -> Optional[List[Optional[Keypoint]]]:
|
||||
keypoints = [
|
||||
Keypoint(x, y, score, i) if score >= 0.3 else None
|
||||
for i, (x, y, score) in enumerate(part)
|
||||
]
|
||||
return (
|
||||
None if all(keypoint is None for keypoint in keypoints) else keypoints
|
||||
)
|
||||
|
||||
def total_score(keypoints: Optional[List[Optional[Keypoint]]]) -> float:
|
||||
return (
|
||||
sum(keypoint.score for keypoint in keypoints if keypoint is not None)
|
||||
if keypoints is not None
|
||||
else 0.0
|
||||
)
|
||||
|
||||
pose_results = []
|
||||
if keypoints_info is None:
|
||||
return pose_results
|
||||
|
||||
for instance in keypoints_info:
|
||||
body_keypoints = format_keypoint_part(instance[:18]) or ([None] * 18)
|
||||
left_hand = format_keypoint_part(instance[92:113])
|
||||
right_hand = format_keypoint_part(instance[113:134])
|
||||
face = format_keypoint_part(instance[24:92])
|
||||
|
||||
# Openpose face consists of 70 points in total, while DWPose only
|
||||
# provides 68 points. Padding the last 2 points.
|
||||
if face is not None:
|
||||
# left eye
|
||||
face.append(body_keypoints[14])
|
||||
# right eye
|
||||
face.append(body_keypoints[15])
|
||||
|
||||
body = BodyResult(
|
||||
body_keypoints, total_score(body_keypoints), len(body_keypoints)
|
||||
)
|
||||
pose_results.append(HumanPoseResult(body, left_hand, right_hand, face))
|
||||
|
||||
return pose_results
|
||||
|
||||
@@ -1,514 +0,0 @@
|
||||
# This folder is modified from the https://github.com/Mikubill/sd-webui-controlnet
|
||||
import os
|
||||
|
||||
import cv2
|
||||
import folder_paths
|
||||
import numpy as np
|
||||
import torch
|
||||
from einops import rearrange
|
||||
|
||||
from .dwpose_utils import DWposeDetector
|
||||
from .zoe.zoedepth.models.zoedepth.zoedepth_v1 import ZoeDepth
|
||||
from .zoe.zoedepth.utils.config import get_config
|
||||
|
||||
remote_onnx_det = "https://huggingface.co/yzd-v/DWPose/resolve/main/yolox_l.onnx"
|
||||
remote_onnx_pose = "https://huggingface.co/yzd-v/DWPose/resolve/main/dw-ll_ucoco_384.onnx"
|
||||
remote_zoe= "https://huggingface.co/lllyasviel/Annotators/resolve/main/ZoeD_M12_N.pt"
|
||||
|
||||
def read_video(video_path):
|
||||
cap = cv2.VideoCapture(video_path)
|
||||
frames = []
|
||||
while cap.isOpened():
|
||||
ret, frame = cap.read()
|
||||
if not ret:
|
||||
break
|
||||
frame = cv2.cvtColor(frame, cv2.COLOR_RGB2BGR)
|
||||
frames.append(frame)
|
||||
cap.release()
|
||||
return frames
|
||||
|
||||
def HWC3(x):
|
||||
assert x.dtype == np.uint8
|
||||
if x.ndim == 2:
|
||||
x = x[:, :, None]
|
||||
assert x.ndim == 3
|
||||
H, W, C = x.shape
|
||||
assert C == 1 or C == 3 or C == 4
|
||||
if C == 3:
|
||||
return x
|
||||
if C == 1:
|
||||
return np.concatenate([x, x, x], axis=2)
|
||||
if C == 4:
|
||||
color = x[:, :, 0:3].astype(np.float32)
|
||||
alpha = x[:, :, 3:4].astype(np.float32) / 255.0
|
||||
y = color * alpha + 255.0 * (1.0 - alpha)
|
||||
y = y.clip(0, 255).astype(np.uint8)
|
||||
return y
|
||||
|
||||
def pad64(x):
|
||||
return int(np.ceil(float(x) / 64.0) * 64 - x)
|
||||
|
||||
def safer_memory(x):
|
||||
# Fix many MAC/AMD problems
|
||||
return np.ascontiguousarray(x.copy()).copy()
|
||||
|
||||
def resize_image_with_pad(input_image, resolution, skip_hwc3=False):
|
||||
if skip_hwc3:
|
||||
img = input_image
|
||||
else:
|
||||
img = HWC3(input_image)
|
||||
H_raw, W_raw, _ = img.shape
|
||||
k = float(resolution) / float(min(H_raw, W_raw))
|
||||
interpolation = cv2.INTER_CUBIC if k > 1 else cv2.INTER_AREA
|
||||
H_target = int(np.round(float(H_raw) * k))
|
||||
W_target = int(np.round(float(W_raw) * k))
|
||||
img = cv2.resize(img, (W_target, H_target), interpolation=interpolation)
|
||||
H_pad, W_pad = pad64(H_target), pad64(W_target)
|
||||
img_padded = np.pad(img, [[0, H_pad], [0, W_pad], [0, 0]], mode='edge')
|
||||
|
||||
def remove_pad(x):
|
||||
return safer_memory(x[:H_target, :W_target])
|
||||
|
||||
return safer_memory(img_padded), remove_pad
|
||||
|
||||
def load_file_from_url(
|
||||
url: str,
|
||||
model_dir: str,
|
||||
progress: bool = True,
|
||||
file_name: str | None = None,
|
||||
hash_prefix: str | None = None,
|
||||
) -> str:
|
||||
"""Download a file from `url` into `model_dir`, using the file present if possible.
|
||||
|
||||
Returns the path to the downloaded file.
|
||||
"""
|
||||
from urllib.parse import urlparse
|
||||
os.makedirs(model_dir, exist_ok=True)
|
||||
if not file_name:
|
||||
parts = urlparse(url)
|
||||
file_name = os.path.basename(parts.path)
|
||||
cached_file = os.path.abspath(os.path.join(model_dir, file_name))
|
||||
if not os.path.exists(cached_file):
|
||||
print(f'Downloading: "{url}" to {cached_file}\n')
|
||||
from torch.hub import download_url_to_file
|
||||
download_url_to_file(url, cached_file, progress=progress, hash_prefix=hash_prefix)
|
||||
return cached_file
|
||||
|
||||
class VideoToCanny:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"input_video": ("IMAGE",),
|
||||
"low_threshold": ("INT", {"default": 100, "min": 0, "max": 255, "step": 1}),
|
||||
"high_threshold": ("INT", {"default": 200, "min": 0, "max": 255, "step": 1}),
|
||||
"video_length": (
|
||||
"INT", {"default": 81, "min": 1, "max": 81, "step": 4}
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES =("images",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "CogVideoXFUNWrapper"
|
||||
|
||||
def process(self, input_video, low_threshold, high_threshold, video_length):
|
||||
def extract_canny_frames(frames):
|
||||
canny_frames = []
|
||||
for frame in frames:
|
||||
gray = cv2.cvtColor(frame, cv2.COLOR_RGB2GRAY)
|
||||
edges = cv2.Canny(gray, low_threshold, high_threshold)
|
||||
edges_colored = cv2.cvtColor(edges, cv2.COLOR_GRAY2RGB)
|
||||
canny_frames.append(edges_colored)
|
||||
return canny_frames
|
||||
|
||||
if type(input_video) is str:
|
||||
video_frames = read_video(input_video)
|
||||
else:
|
||||
video_frames = np.array(input_video * 255, np.uint8)[:video_length]
|
||||
output_video = extract_canny_frames(video_frames)
|
||||
output_video = torch.from_numpy(np.array(output_video)) / 255
|
||||
return (output_video,)
|
||||
|
||||
class VideoToDepth:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"input_video": ("IMAGE",),
|
||||
"video_length": (
|
||||
"INT", {"default": 81, "min": 1, "max": 81, "step": 4}
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES = ("images",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "CogVideoXFUNWrapper"
|
||||
|
||||
|
||||
def process_frame(self, model, image, device, weight_dtype):
|
||||
with torch.no_grad():
|
||||
image, remove_pad = resize_image_with_pad(image, 512)
|
||||
image_depth = image
|
||||
with torch.no_grad():
|
||||
image_depth = torch.from_numpy(image_depth).to(device, weight_dtype)
|
||||
image_depth = image_depth / 255.0
|
||||
image_depth = rearrange(image_depth, 'h w c -> 1 c h w')
|
||||
depth = model.infer(image_depth)
|
||||
|
||||
depth = depth[0, 0].cpu().numpy()
|
||||
|
||||
vmin = np.percentile(depth, 2)
|
||||
vmax = np.percentile(depth, 85)
|
||||
|
||||
depth -= vmin
|
||||
depth /= vmax - vmin
|
||||
depth = 1.0 - depth
|
||||
depth_image = (depth * 255.0).clip(0, 255).astype(np.uint8)
|
||||
image = remove_pad(depth_image)
|
||||
image = HWC3(image)
|
||||
return image
|
||||
|
||||
def process(self, input_video, video_length):
|
||||
model = ZoeDepth.build_from_config(get_config("zoedepth", "infer"))
|
||||
|
||||
# Detect model is existing or not
|
||||
possible_folders = ["CogVideoX_Fun/Third_Party", "Fun_Models/Third_Party", "VideoX_Fun/Third_Party"] # Possible folder names to check
|
||||
|
||||
# Check if the model exists in any of the possible folders within folder_paths.models_dir
|
||||
zoe_model_path = "ZoeD_M12_N.pt"
|
||||
for folder in possible_folders:
|
||||
candidate_path = os.path.join(folder_paths.models_dir, folder, zoe_model_path)
|
||||
if os.path.exists(candidate_path):
|
||||
zoe_model_path = candidate_path
|
||||
break
|
||||
if not os.path.exists(zoe_model_path):
|
||||
load_file_from_url(remote_zoe, model_dir=os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
|
||||
zoe_model_path = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", zoe_model_path)
|
||||
|
||||
model.load_state_dict(
|
||||
torch.load(zoe_model_path, map_location="cpu")['model'],
|
||||
strict=False
|
||||
)
|
||||
if torch.cuda.is_available():
|
||||
device = "cuda"
|
||||
weight_dtype = torch.float32
|
||||
else:
|
||||
device = "cpu"
|
||||
weight_dtype = torch.float32
|
||||
model = model.to(device=device, dtype=weight_dtype).eval().requires_grad_(False)
|
||||
|
||||
if isinstance(input_video, str):
|
||||
video_frames = read_video(input_video)
|
||||
else:
|
||||
video_frames = np.array(input_video * 255, np.uint8)[:video_length]
|
||||
|
||||
output_video = [self.process_frame(model, frame, device, weight_dtype) for frame in video_frames]
|
||||
output_video = torch.from_numpy(np.array(output_video)) / 255
|
||||
|
||||
return (output_video,)
|
||||
|
||||
|
||||
class VideoToPose:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"input_video": ("IMAGE",),
|
||||
"video_length": (
|
||||
"INT", {"default": 81, "min": 1, "max": 81, "step": 4}
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES = ("images",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "CogVideoXFUNWrapper"
|
||||
|
||||
def process_frame(self, model, image):
|
||||
with torch.no_grad():
|
||||
image, remove_pad = resize_image_with_pad(image, 512)
|
||||
pose_image = model(image)
|
||||
image = remove_pad(pose_image)
|
||||
image = HWC3(image)
|
||||
return image
|
||||
|
||||
def process(self, input_video, video_length):
|
||||
# Detect model is existing or not
|
||||
possible_folders = ["CogVideoX_Fun/Third_Party", "Fun_Models/Third_Party", "VideoX_Fun/Third_Party"] # Possible folder names to check
|
||||
|
||||
# Check if the model exists in any of the possible folders within folder_paths.models_dir
|
||||
onnx_det = "yolox_l.onnx"
|
||||
for folder in possible_folders:
|
||||
candidate_path = os.path.join(folder_paths.models_dir, folder, onnx_det)
|
||||
if os.path.exists(candidate_path):
|
||||
onnx_det = candidate_path
|
||||
break
|
||||
if not os.path.exists(onnx_det):
|
||||
load_file_from_url(remote_onnx_det, os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
|
||||
onnx_det = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", onnx_det)
|
||||
|
||||
onnx_pose = "dw-ll_ucoco_384.onnx"
|
||||
for folder in possible_folders:
|
||||
candidate_path = os.path.join(folder_paths.models_dir, folder, onnx_pose)
|
||||
if os.path.exists(candidate_path):
|
||||
onnx_pose = candidate_path
|
||||
break
|
||||
if not os.path.exists(onnx_pose):
|
||||
load_file_from_url(remote_onnx_pose, os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
|
||||
onnx_pose = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", onnx_pose)
|
||||
|
||||
model = DWposeDetector(onnx_det, onnx_pose)
|
||||
|
||||
if isinstance(input_video, str):
|
||||
video_frames = read_video(input_video)
|
||||
else:
|
||||
video_frames = np.array(input_video * 255, np.uint8)[:video_length]
|
||||
|
||||
output_video = [self.process_frame(model, frame) for frame in video_frames]
|
||||
output_video = torch.from_numpy(np.array(output_video)) / 255
|
||||
return (output_video,)
|
||||
|
||||
|
||||
class ImageToCanny:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"input_image": ("IMAGE",),
|
||||
"low_threshold": ("INT", {"default": 100, "min": 0, "max": 255, "step": 1}),
|
||||
"high_threshold": ("INT", {"default": 200, "min": 0, "max": 255, "step": 1}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES = ("image",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "CogVideoXFUNWrapper"
|
||||
|
||||
def process(self, input_image, low_threshold, high_threshold):
|
||||
# Convert input image to numpy array
|
||||
image = np.array(input_image * 255, np.uint8)
|
||||
|
||||
# If it's a batch of images, only process the first one
|
||||
if len(image.shape) == 4:
|
||||
image = image[0]
|
||||
|
||||
# Convert to grayscale
|
||||
gray = cv2.cvtColor(image, cv2.COLOR_RGB2GRAY)
|
||||
|
||||
# Canny edge detection
|
||||
edges = cv2.Canny(gray, low_threshold, high_threshold)
|
||||
|
||||
# Convert back to RGB format
|
||||
edges_colored = cv2.cvtColor(edges, cv2.COLOR_GRAY2RGB)
|
||||
|
||||
# Convert to torch tensor and normalize
|
||||
output_image = torch.from_numpy(edges_colored).float() / 255.0
|
||||
|
||||
# Add batch dimension
|
||||
output_image = output_image.unsqueeze(0)
|
||||
|
||||
return (output_image,)
|
||||
|
||||
|
||||
class ImageToDepth:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"input_image": ("IMAGE",),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES = ("image",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "CogVideoXFUNWrapper"
|
||||
|
||||
def process_single_image(self, model, image, device, weight_dtype):
|
||||
"""
|
||||
Process a single image to generate depth map
|
||||
|
||||
Args:
|
||||
model: ZoeDepth model instance
|
||||
image: Input image as numpy array
|
||||
device: Computing device (cuda/cpu)
|
||||
weight_dtype: Data type for model weights
|
||||
|
||||
Returns:
|
||||
Processed depth map as numpy array
|
||||
"""
|
||||
with torch.no_grad():
|
||||
# Resize image with padding to match model input size
|
||||
image, remove_pad = resize_image_with_pad(image, 512)
|
||||
image_depth = image
|
||||
|
||||
with torch.no_grad():
|
||||
# Convert to tensor and normalize
|
||||
image_depth = torch.from_numpy(image_depth).to(device, weight_dtype)
|
||||
image_depth = image_depth / 255.0
|
||||
# Rearrange dimensions for model input
|
||||
image_depth = rearrange(image_depth, 'h w c -> 1 c h w')
|
||||
# Infer depth map
|
||||
depth = model.infer(image_depth)
|
||||
|
||||
depth = depth[0, 0].cpu().numpy()
|
||||
|
||||
# Normalize depth values using percentiles
|
||||
vmin = np.percentile(depth, 2)
|
||||
vmax = np.percentile(depth, 85)
|
||||
|
||||
depth -= vmin
|
||||
depth /= vmax - vmin
|
||||
depth = 1.0 - depth
|
||||
# Convert to uint8 format
|
||||
depth_image = (depth * 255.0).clip(0, 255).astype(np.uint8)
|
||||
|
||||
# Remove padding and ensure 3-channel output
|
||||
image = remove_pad(depth_image)
|
||||
image = HWC3(image)
|
||||
return image
|
||||
|
||||
def process(self, input_image):
|
||||
# Initialize ZoeDepth model
|
||||
model = ZoeDepth.build_from_config(get_config("zoedepth", "infer"))
|
||||
|
||||
# Detect model path from possible folders
|
||||
possible_folders = ["CogVideoX_Fun/Third_Party", "Fun_Models/Third_Party", "VideoX_Fun/Third_Party"]
|
||||
zoe_model_path = "ZoeD_M12_N.pt"
|
||||
|
||||
# Search for existing model file
|
||||
for folder in possible_folders:
|
||||
candidate_path = os.path.join(folder_paths.models_dir, folder, zoe_model_path)
|
||||
if os.path.exists(candidate_path):
|
||||
zoe_model_path = candidate_path
|
||||
break
|
||||
|
||||
# Download model if not found locally
|
||||
if not os.path.exists(zoe_model_path):
|
||||
load_file_from_url(remote_zoe, model_dir=os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
|
||||
zoe_model_path = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", zoe_model_path)
|
||||
|
||||
# Load model weights
|
||||
model.load_state_dict(
|
||||
torch.load(zoe_model_path, map_location="cpu")['model'],
|
||||
strict=False
|
||||
)
|
||||
|
||||
# Set device and data type
|
||||
if torch.cuda.is_available():
|
||||
device = "cuda"
|
||||
weight_dtype = torch.float32
|
||||
else:
|
||||
device = "cpu"
|
||||
weight_dtype = torch.float32
|
||||
|
||||
# Move model to device and set to evaluation mode
|
||||
model = model.to(device=device, dtype=weight_dtype).eval().requires_grad_(False)
|
||||
|
||||
# Convert input image to numpy array
|
||||
image = np.array(input_image * 255, np.uint8)
|
||||
|
||||
# If it's a batch of images, only process the first one
|
||||
if len(image.shape) == 4:
|
||||
image = image[0]
|
||||
|
||||
# Process image to generate depth map
|
||||
output_image = self.process_single_image(model, image, device, weight_dtype)
|
||||
output_image = torch.from_numpy(output_image).float() / 255.0
|
||||
|
||||
# Add batch dimension
|
||||
output_image = output_image.unsqueeze(0)
|
||||
|
||||
return (output_image,)
|
||||
|
||||
|
||||
class ImageToPose:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"input_image": ("IMAGE",),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES = ("image",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "CogVideoXFUNWrapper"
|
||||
|
||||
def process_single_image(self, model, image):
|
||||
"""
|
||||
Process a single image to detect and draw pose keypoints
|
||||
|
||||
Args:
|
||||
model: DWPose detector model instance
|
||||
image: Input image as numpy array
|
||||
|
||||
Returns:
|
||||
Image with pose keypoints drawn as numpy array
|
||||
"""
|
||||
with torch.no_grad():
|
||||
# Resize image with padding to match model input size
|
||||
image, remove_pad = resize_image_with_pad(image, 512)
|
||||
# Detect and draw pose keypoints
|
||||
pose_image = model(image)
|
||||
# Remove padding
|
||||
image = remove_pad(pose_image)
|
||||
# Ensure 3-channel output
|
||||
image = HWC3(image)
|
||||
return image
|
||||
|
||||
def process(self, input_image):
|
||||
# Detect model paths from possible folders
|
||||
possible_folders = ["CogVideoX_Fun/Third_Party", "Fun_Models/Third_Party", "VideoX_Fun/Third_Party"]
|
||||
|
||||
# Search for detection model (yolox_l.onnx)
|
||||
onnx_det = "yolox_l.onnx"
|
||||
for folder in possible_folders:
|
||||
candidate_path = os.path.join(folder_paths.models_dir, folder, onnx_det)
|
||||
if os.path.exists(candidate_path):
|
||||
onnx_det = candidate_path
|
||||
break
|
||||
|
||||
# Download detection model if not found locally
|
||||
if not os.path.exists(onnx_det):
|
||||
load_file_from_url(remote_onnx_det, os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
|
||||
onnx_det = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", onnx_det)
|
||||
|
||||
# Search for pose model (dw-ll_ucoco_384.onnx)
|
||||
onnx_pose = "dw-ll_ucoco_384.onnx"
|
||||
for folder in possible_folders:
|
||||
candidate_path = os.path.join(folder_paths.models_dir, folder, onnx_pose)
|
||||
if os.path.exists(candidate_path):
|
||||
onnx_pose = candidate_path
|
||||
break
|
||||
|
||||
# Download pose model if not found locally
|
||||
if not os.path.exists(onnx_pose):
|
||||
load_file_from_url(remote_onnx_pose, os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
|
||||
onnx_pose = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", onnx_pose)
|
||||
|
||||
# Initialize DWPose detector model
|
||||
model = DWposeDetector(onnx_det, onnx_pose)
|
||||
|
||||
# Convert input image to numpy array
|
||||
image = np.array(input_image * 255, np.uint8)
|
||||
|
||||
# If it's a batch of images, only process the first one
|
||||
if len(image.shape) == 4:
|
||||
image = image[0]
|
||||
|
||||
# Process image to detect and draw pose
|
||||
output_image = self.process_single_image(model, image)
|
||||
output_image = torch.from_numpy(output_image).float() / 255.0
|
||||
|
||||
# Add batch dimension for compatibility
|
||||
output_image = output_image.unsqueeze(0)
|
||||
|
||||
return (output_image,)
|
||||
@@ -1,21 +0,0 @@
|
||||
MIT License
|
||||
|
||||
Copyright (c) 2022 Intelligent Systems Lab Org
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
of this software and associated documentation files (the "Software"), to deal
|
||||
in the Software without restriction, including without limitation the rights
|
||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
copies of the Software, and to permit persons to whom the Software is
|
||||
furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all
|
||||
copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
SOFTWARE.
|
||||
@@ -1,41 +0,0 @@
|
||||
# This folder is modified from the https://github.com/Mikubill/sd-webui-controlnet
|
||||
import os
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import torch
|
||||
from einops import rearrange
|
||||
from torch import nn
|
||||
|
||||
from .zoedepth.models.zoedepth.zoedepth_v1 import ZoeDepth
|
||||
from .zoedepth.utils.config import get_config
|
||||
|
||||
|
||||
class ZoeDetector(nn.Module):
|
||||
def __init__(self, model_path):
|
||||
conf = get_config("zoedepth", "infer")
|
||||
model = ZoeDepth.build_from_config(conf)
|
||||
model.load_state_dict(torch.load(model_path, map_location=model.device)['model'])
|
||||
model.eval()
|
||||
self.model = model
|
||||
|
||||
def __call__(self, input_image):
|
||||
assert input_image.ndim == 3
|
||||
image_depth = input_image
|
||||
with torch.no_grad():
|
||||
image_depth = torch.from_numpy(image_depth).float()
|
||||
image_depth = image_depth / 255.0
|
||||
image_depth = rearrange(image_depth, 'h w c -> 1 c h w')
|
||||
depth = self.model.infer(image_depth)
|
||||
|
||||
depth = depth[0, 0].cpu().numpy()
|
||||
|
||||
vmin = np.percentile(depth, 2)
|
||||
vmax = np.percentile(depth, 85)
|
||||
|
||||
depth -= vmin
|
||||
depth /= vmax - vmin
|
||||
depth = 1.0 - depth
|
||||
depth_image = (depth * 255.0).clip(0, 255).astype(np.uint8)
|
||||
|
||||
return depth_image
|
||||
@@ -1,24 +0,0 @@
|
||||
# MIT License
|
||||
|
||||
# Copyright (c) 2022 Intelligent Systems Lab Org
|
||||
|
||||
# Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
# of this software and associated documentation files (the "Software"), to deal
|
||||
# in the Software without restriction, including without limitation the rights
|
||||
# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
# copies of the Software, and to permit persons to whom the Software is
|
||||
# furnished to do so, subject to the following conditions:
|
||||
|
||||
# The above copyright notice and this permission notice shall be included in all
|
||||
# copies or substantial portions of the Software.
|
||||
|
||||
# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
# SOFTWARE.
|
||||
|
||||
# File author: Shariq Farooq Bhat
|
||||
|
||||
@@ -1,380 +0,0 @@
|
||||
# MIT License
|
||||
import os
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from torchvision.transforms import Normalize
|
||||
|
||||
# Copyright (c) 2022 Intelligent Systems Lab Org
|
||||
|
||||
# Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
# of this software and associated documentation files (the "Software"), to deal
|
||||
# in the Software without restriction, including without limitation the rights
|
||||
# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
# copies of the Software, and to permit persons to whom the Software is
|
||||
# furnished to do so, subject to the following conditions:
|
||||
|
||||
# The above copyright notice and this permission notice shall be included in all
|
||||
# copies or substantial portions of the Software.
|
||||
|
||||
# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
# SOFTWARE.
|
||||
|
||||
# File author: Shariq Farooq Bhat
|
||||
|
||||
|
||||
|
||||
def denormalize(x):
|
||||
"""Reverses the imagenet normalization applied to the input.
|
||||
|
||||
Args:
|
||||
x (torch.Tensor - shape(N,3,H,W)): input tensor
|
||||
|
||||
Returns:
|
||||
torch.Tensor - shape(N,3,H,W): Denormalized input
|
||||
"""
|
||||
mean = torch.Tensor([0.485, 0.456, 0.406]).view(1, 3, 1, 1).to(x.device)
|
||||
std = torch.Tensor([0.229, 0.224, 0.225]).view(1, 3, 1, 1).to(x.device)
|
||||
return x * std + mean
|
||||
|
||||
def get_activation(name, bank):
|
||||
def hook(model, input, output):
|
||||
bank[name] = output
|
||||
return hook
|
||||
|
||||
|
||||
class Resize(object):
|
||||
"""Resize sample to given size (width, height).
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
width,
|
||||
height,
|
||||
resize_target=True,
|
||||
keep_aspect_ratio=False,
|
||||
ensure_multiple_of=1,
|
||||
resize_method="lower_bound",
|
||||
):
|
||||
"""Init.
|
||||
Args:
|
||||
width (int): desired output width
|
||||
height (int): desired output height
|
||||
resize_target (bool, optional):
|
||||
True: Resize the full sample (image, mask, target).
|
||||
False: Resize image only.
|
||||
Defaults to True.
|
||||
keep_aspect_ratio (bool, optional):
|
||||
True: Keep the aspect ratio of the input sample.
|
||||
Output sample might not have the given width and height, and
|
||||
resize behaviour depends on the parameter 'resize_method'.
|
||||
Defaults to False.
|
||||
ensure_multiple_of (int, optional):
|
||||
Output width and height is constrained to be multiple of this parameter.
|
||||
Defaults to 1.
|
||||
resize_method (str, optional):
|
||||
"lower_bound": Output will be at least as large as the given size.
|
||||
"upper_bound": Output will be at max as large as the given size. (Output size might be smaller than given size.)
|
||||
"minimal": Scale as least as possible. (Output size might be smaller than given size.)
|
||||
Defaults to "lower_bound".
|
||||
"""
|
||||
print("Params passed to Resize transform:")
|
||||
print("\twidth: ", width)
|
||||
print("\theight: ", height)
|
||||
print("\tresize_target: ", resize_target)
|
||||
print("\tkeep_aspect_ratio: ", keep_aspect_ratio)
|
||||
print("\tensure_multiple_of: ", ensure_multiple_of)
|
||||
print("\tresize_method: ", resize_method)
|
||||
|
||||
self.__width = width
|
||||
self.__height = height
|
||||
|
||||
self.__keep_aspect_ratio = keep_aspect_ratio
|
||||
self.__multiple_of = ensure_multiple_of
|
||||
self.__resize_method = resize_method
|
||||
|
||||
def constrain_to_multiple_of(self, x, min_val=0, max_val=None):
|
||||
y = (np.round(x / self.__multiple_of) * self.__multiple_of).astype(int)
|
||||
|
||||
if max_val is not None and y > max_val:
|
||||
y = (np.floor(x / self.__multiple_of)
|
||||
* self.__multiple_of).astype(int)
|
||||
|
||||
if y < min_val:
|
||||
y = (np.ceil(x / self.__multiple_of)
|
||||
* self.__multiple_of).astype(int)
|
||||
|
||||
return y
|
||||
|
||||
def get_size(self, width, height):
|
||||
# determine new height and width
|
||||
scale_height = self.__height / height
|
||||
scale_width = self.__width / width
|
||||
|
||||
if self.__keep_aspect_ratio:
|
||||
if self.__resize_method == "lower_bound":
|
||||
# scale such that output size is lower bound
|
||||
if scale_width > scale_height:
|
||||
# fit width
|
||||
scale_height = scale_width
|
||||
else:
|
||||
# fit height
|
||||
scale_width = scale_height
|
||||
elif self.__resize_method == "upper_bound":
|
||||
# scale such that output size is upper bound
|
||||
if scale_width < scale_height:
|
||||
# fit width
|
||||
scale_height = scale_width
|
||||
else:
|
||||
# fit height
|
||||
scale_width = scale_height
|
||||
elif self.__resize_method == "minimal":
|
||||
# scale as least as possbile
|
||||
if abs(1 - scale_width) < abs(1 - scale_height):
|
||||
# fit width
|
||||
scale_height = scale_width
|
||||
else:
|
||||
# fit height
|
||||
scale_width = scale_height
|
||||
else:
|
||||
raise ValueError(
|
||||
f"resize_method {self.__resize_method} not implemented"
|
||||
)
|
||||
|
||||
if self.__resize_method == "lower_bound":
|
||||
new_height = self.constrain_to_multiple_of(
|
||||
scale_height * height, min_val=self.__height
|
||||
)
|
||||
new_width = self.constrain_to_multiple_of(
|
||||
scale_width * width, min_val=self.__width
|
||||
)
|
||||
elif self.__resize_method == "upper_bound":
|
||||
new_height = self.constrain_to_multiple_of(
|
||||
scale_height * height, max_val=self.__height
|
||||
)
|
||||
new_width = self.constrain_to_multiple_of(
|
||||
scale_width * width, max_val=self.__width
|
||||
)
|
||||
elif self.__resize_method == "minimal":
|
||||
new_height = self.constrain_to_multiple_of(scale_height * height)
|
||||
new_width = self.constrain_to_multiple_of(scale_width * width)
|
||||
else:
|
||||
raise ValueError(
|
||||
f"resize_method {self.__resize_method} not implemented")
|
||||
|
||||
return (new_width, new_height)
|
||||
|
||||
def __call__(self, x):
|
||||
width, height = self.get_size(*x.shape[-2:][::-1])
|
||||
return nn.functional.interpolate(x, (int(height), int(width)), mode='bilinear', align_corners=True)
|
||||
|
||||
class PrepForMidas(object):
|
||||
def __init__(self, resize_mode="minimal", keep_aspect_ratio=True, img_size=384, do_resize=True):
|
||||
if isinstance(img_size, int):
|
||||
img_size = (img_size, img_size)
|
||||
net_h, net_w = img_size
|
||||
self.normalization = Normalize(
|
||||
mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
|
||||
self.resizer = Resize(net_w, net_h, keep_aspect_ratio=keep_aspect_ratio, ensure_multiple_of=32, resize_method=resize_mode) \
|
||||
if do_resize else nn.Identity()
|
||||
|
||||
def __call__(self, x):
|
||||
return self.normalization(self.resizer(x))
|
||||
|
||||
|
||||
class MidasCore(nn.Module):
|
||||
def __init__(self, midas, trainable=False, fetch_features=True, layer_names=('out_conv', 'l4_rn', 'r4', 'r3', 'r2', 'r1'), freeze_bn=False, keep_aspect_ratio=True,
|
||||
img_size=384, **kwargs):
|
||||
"""Midas Base model used for multi-scale feature extraction.
|
||||
|
||||
Args:
|
||||
midas (torch.nn.Module): Midas model.
|
||||
trainable (bool, optional): Train midas model. Defaults to False.
|
||||
fetch_features (bool, optional): Extract multi-scale features. Defaults to True.
|
||||
layer_names (tuple, optional): Layers used for feature extraction. Order = (head output features, last layer features, ...decoder features). Defaults to ('out_conv', 'l4_rn', 'r4', 'r3', 'r2', 'r1').
|
||||
freeze_bn (bool, optional): Freeze BatchNorm. Generally results in better finetuning performance. Defaults to False.
|
||||
keep_aspect_ratio (bool, optional): Keep the aspect ratio of input images while resizing. Defaults to True.
|
||||
img_size (int, tuple, optional): Input resolution. Defaults to 384.
|
||||
"""
|
||||
super().__init__()
|
||||
self.core = midas
|
||||
self.output_channels = None
|
||||
self.core_out = {}
|
||||
self.trainable = trainable
|
||||
self.fetch_features = fetch_features
|
||||
# midas.scratch.output_conv = nn.Identity()
|
||||
self.handles = []
|
||||
# self.layer_names = ['out_conv','l4_rn', 'r4', 'r3', 'r2', 'r1']
|
||||
self.layer_names = layer_names
|
||||
|
||||
self.set_trainable(trainable)
|
||||
self.set_fetch_features(fetch_features)
|
||||
|
||||
self.prep = PrepForMidas(keep_aspect_ratio=keep_aspect_ratio,
|
||||
img_size=img_size, do_resize=kwargs.get('do_resize', True))
|
||||
|
||||
if freeze_bn:
|
||||
self.freeze_bn()
|
||||
|
||||
def set_trainable(self, trainable):
|
||||
self.trainable = trainable
|
||||
if trainable:
|
||||
self.unfreeze()
|
||||
else:
|
||||
self.freeze()
|
||||
return self
|
||||
|
||||
def set_fetch_features(self, fetch_features):
|
||||
self.fetch_features = fetch_features
|
||||
if fetch_features:
|
||||
if len(self.handles) == 0:
|
||||
self.attach_hooks(self.core)
|
||||
else:
|
||||
self.remove_hooks()
|
||||
return self
|
||||
|
||||
def freeze(self):
|
||||
for p in self.parameters():
|
||||
p.requires_grad = False
|
||||
self.trainable = False
|
||||
return self
|
||||
|
||||
def unfreeze(self):
|
||||
for p in self.parameters():
|
||||
p.requires_grad = True
|
||||
self.trainable = True
|
||||
return self
|
||||
|
||||
def freeze_bn(self):
|
||||
for m in self.modules():
|
||||
if isinstance(m, nn.BatchNorm2d):
|
||||
m.eval()
|
||||
return self
|
||||
|
||||
def forward(self, x, denorm=False, return_rel_depth=False):
|
||||
with torch.no_grad():
|
||||
if denorm:
|
||||
x = denormalize(x)
|
||||
x = self.prep(x)
|
||||
# print("Shape after prep: ", x.shape)
|
||||
|
||||
with torch.set_grad_enabled(self.trainable):
|
||||
|
||||
# print("Input size to Midascore", x.shape)
|
||||
rel_depth = self.core(x)
|
||||
# print("Output from midas shape", rel_depth.shape)
|
||||
if not self.fetch_features:
|
||||
return rel_depth
|
||||
out = [self.core_out[k] for k in self.layer_names]
|
||||
|
||||
if return_rel_depth:
|
||||
return rel_depth, out
|
||||
return out
|
||||
|
||||
def get_rel_pos_params(self):
|
||||
for name, p in self.core.pretrained.named_parameters():
|
||||
if "relative_position" in name:
|
||||
yield p
|
||||
|
||||
def get_enc_params_except_rel_pos(self):
|
||||
for name, p in self.core.pretrained.named_parameters():
|
||||
if "relative_position" not in name:
|
||||
yield p
|
||||
|
||||
def freeze_encoder(self, freeze_rel_pos=False):
|
||||
if freeze_rel_pos:
|
||||
for p in self.core.pretrained.parameters():
|
||||
p.requires_grad = False
|
||||
else:
|
||||
for p in self.get_enc_params_except_rel_pos():
|
||||
p.requires_grad = False
|
||||
return self
|
||||
|
||||
def attach_hooks(self, midas):
|
||||
if len(self.handles) > 0:
|
||||
self.remove_hooks()
|
||||
if "out_conv" in self.layer_names:
|
||||
self.handles.append(list(midas.scratch.output_conv.children())[
|
||||
3].register_forward_hook(get_activation("out_conv", self.core_out)))
|
||||
if "r4" in self.layer_names:
|
||||
self.handles.append(midas.scratch.refinenet4.register_forward_hook(
|
||||
get_activation("r4", self.core_out)))
|
||||
if "r3" in self.layer_names:
|
||||
self.handles.append(midas.scratch.refinenet3.register_forward_hook(
|
||||
get_activation("r3", self.core_out)))
|
||||
if "r2" in self.layer_names:
|
||||
self.handles.append(midas.scratch.refinenet2.register_forward_hook(
|
||||
get_activation("r2", self.core_out)))
|
||||
if "r1" in self.layer_names:
|
||||
self.handles.append(midas.scratch.refinenet1.register_forward_hook(
|
||||
get_activation("r1", self.core_out)))
|
||||
if "l4_rn" in self.layer_names:
|
||||
self.handles.append(midas.scratch.layer4_rn.register_forward_hook(
|
||||
get_activation("l4_rn", self.core_out)))
|
||||
|
||||
return self
|
||||
|
||||
def remove_hooks(self):
|
||||
for h in self.handles:
|
||||
h.remove()
|
||||
return self
|
||||
|
||||
def __del__(self):
|
||||
self.remove_hooks()
|
||||
|
||||
def set_output_channels(self, model_type):
|
||||
self.output_channels = MIDAS_SETTINGS[model_type]
|
||||
|
||||
@staticmethod
|
||||
def build(midas_model_type="DPT_BEiT_L_384", train_midas=False, use_pretrained_midas=True, fetch_features=False, freeze_bn=True, force_keep_ar=False, force_reload=False, **kwargs):
|
||||
if midas_model_type not in MIDAS_SETTINGS:
|
||||
raise ValueError(
|
||||
f"Invalid model type: {midas_model_type}. Must be one of {list(MIDAS_SETTINGS.keys())}")
|
||||
if "img_size" in kwargs:
|
||||
kwargs = MidasCore.parse_img_size(kwargs)
|
||||
img_size = kwargs.pop("img_size", [384, 384])
|
||||
print("img_size", img_size)
|
||||
midas_path = os.path.join(os.path.dirname(__file__), 'midas_repo')
|
||||
midas = torch.hub.load(midas_path, midas_model_type,
|
||||
pretrained=use_pretrained_midas, force_reload=force_reload, source='local')
|
||||
kwargs.update({'keep_aspect_ratio': force_keep_ar})
|
||||
midas_core = MidasCore(midas, trainable=train_midas, fetch_features=fetch_features,
|
||||
freeze_bn=freeze_bn, img_size=img_size, **kwargs)
|
||||
midas_core.set_output_channels(midas_model_type)
|
||||
return midas_core
|
||||
|
||||
@staticmethod
|
||||
def build_from_config(config):
|
||||
return MidasCore.build(**config)
|
||||
|
||||
@staticmethod
|
||||
def parse_img_size(config):
|
||||
assert 'img_size' in config
|
||||
if isinstance(config['img_size'], str):
|
||||
assert "," in config['img_size'], "img_size should be a string with comma separated img_size=H,W"
|
||||
config['img_size'] = list(map(int, config['img_size'].split(",")))
|
||||
assert len(
|
||||
config['img_size']) == 2, "img_size should be a string with comma separated img_size=H,W"
|
||||
elif isinstance(config['img_size'], int):
|
||||
config['img_size'] = [config['img_size'], config['img_size']]
|
||||
else:
|
||||
assert isinstance(config['img_size'], list) and len(
|
||||
config['img_size']) == 2, "img_size should be a list of H,W"
|
||||
return config
|
||||
|
||||
|
||||
nchannels2models = {
|
||||
tuple([256]*5): ["DPT_BEiT_L_384", "DPT_BEiT_L_512", "DPT_BEiT_B_384", "DPT_SwinV2_L_384", "DPT_SwinV2_B_384", "DPT_SwinV2_T_256", "DPT_Large", "DPT_Hybrid"],
|
||||
(512, 256, 128, 64, 64): ["MiDaS_small"]
|
||||
}
|
||||
|
||||
# Model name to number of output channels
|
||||
MIDAS_SETTINGS = {m: k for k, v in nchannels2models.items()
|
||||
for m in v
|
||||
}
|
||||