Compare commits
3
Commits
main
..
README_Bug
| Author | SHA1 | Date | |
|---|---|---|---|
 bubbliiiing |
a28de73185 | ||
|
bubbliiiing
|
f537e5d2c6 | ||
|
bubbliiiing
|
50d177d8f9 |
@@ -26,6 +26,24 @@ English | [简体中文](./README_zh-CN.md) | [日本語](./README_ja-JP.md)
|
||||
# I. Introduction
|
||||
VideoX-Fun is a video generation pipeline that can be used to generate AI images and videos, as well as to train baseline and Lora models for Diffusion Transformer. We support direct prediction from pre-trained baseline models to generate videos with different resolutions, durations, and FPS. Additionally, we also support users in training their own baseline and Lora models to perform specific style transformations.
|
||||
|
||||
What's New:
|
||||
- Added support for Wan 2.2 series models, Wan-VACE control model, Fantasy Talking digital human model, Qwen-Image, Flux image generation models, and more. [2025.10.16]
|
||||
- Update Wan2.1-Fun-V1.1: Support for 14B and 1.3B model Control + Reference Image models, support for camera control, and the Inpaint model has been retrained for improved performance. [2025.04.25]
|
||||
- Update Wan2.1-Fun-V1.0: Support I2V and Control models for 14B and 1.3B models, with support for start and end frame prediction. [2025.03.26]
|
||||
- Update CogVideoX-Fun-V1.5: Upload I2V model and related training/prediction code. [2024.12.16]
|
||||
- Reward Lora Support: Train Lora using reward backpropagation techniques to optimize generated videos, making them better aligned with human preferences. [More Information](scripts/README_TRAIN_REWARD.md). New version of the control model supports various control conditions such as Canny, Depth, Pose, MLSD, etc. [2024.11.21]
|
||||
- Diffusers Support: CogVideoX-Fun Control is now supported in diffusers. Thanks to [a-r-r-o-w](https://github.com/a-r-r-o-w) for contributing support in this [PR](https://github.com/huggingface/diffusers/pull/9671). Check out the [documentation](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cogvideox) for more details. [2024.10.16]
|
||||
- Update CogVideoX-Fun-V1.1: Retrain i2v model, add Noise to increase the motion amplitude of the video. Upload control model training code and Control model. [2024.09.29]
|
||||
- Update CogVideoX-Fun-V1.0: Initial code release! Now supports Windows and Linux. Supports video generation at arbitrary resolutions from 256x256x49 to 1024x1024x49 for 2B and 5B models. [2024.09.18]
|
||||
|
||||
Function:
|
||||
- [Data Preprocessing](#data-preprocess)
|
||||
- [Train DiT](#dit-train)
|
||||
- [Video Generation](#video-gen)
|
||||
|
||||
Our UI interface is as follows:
|
||||
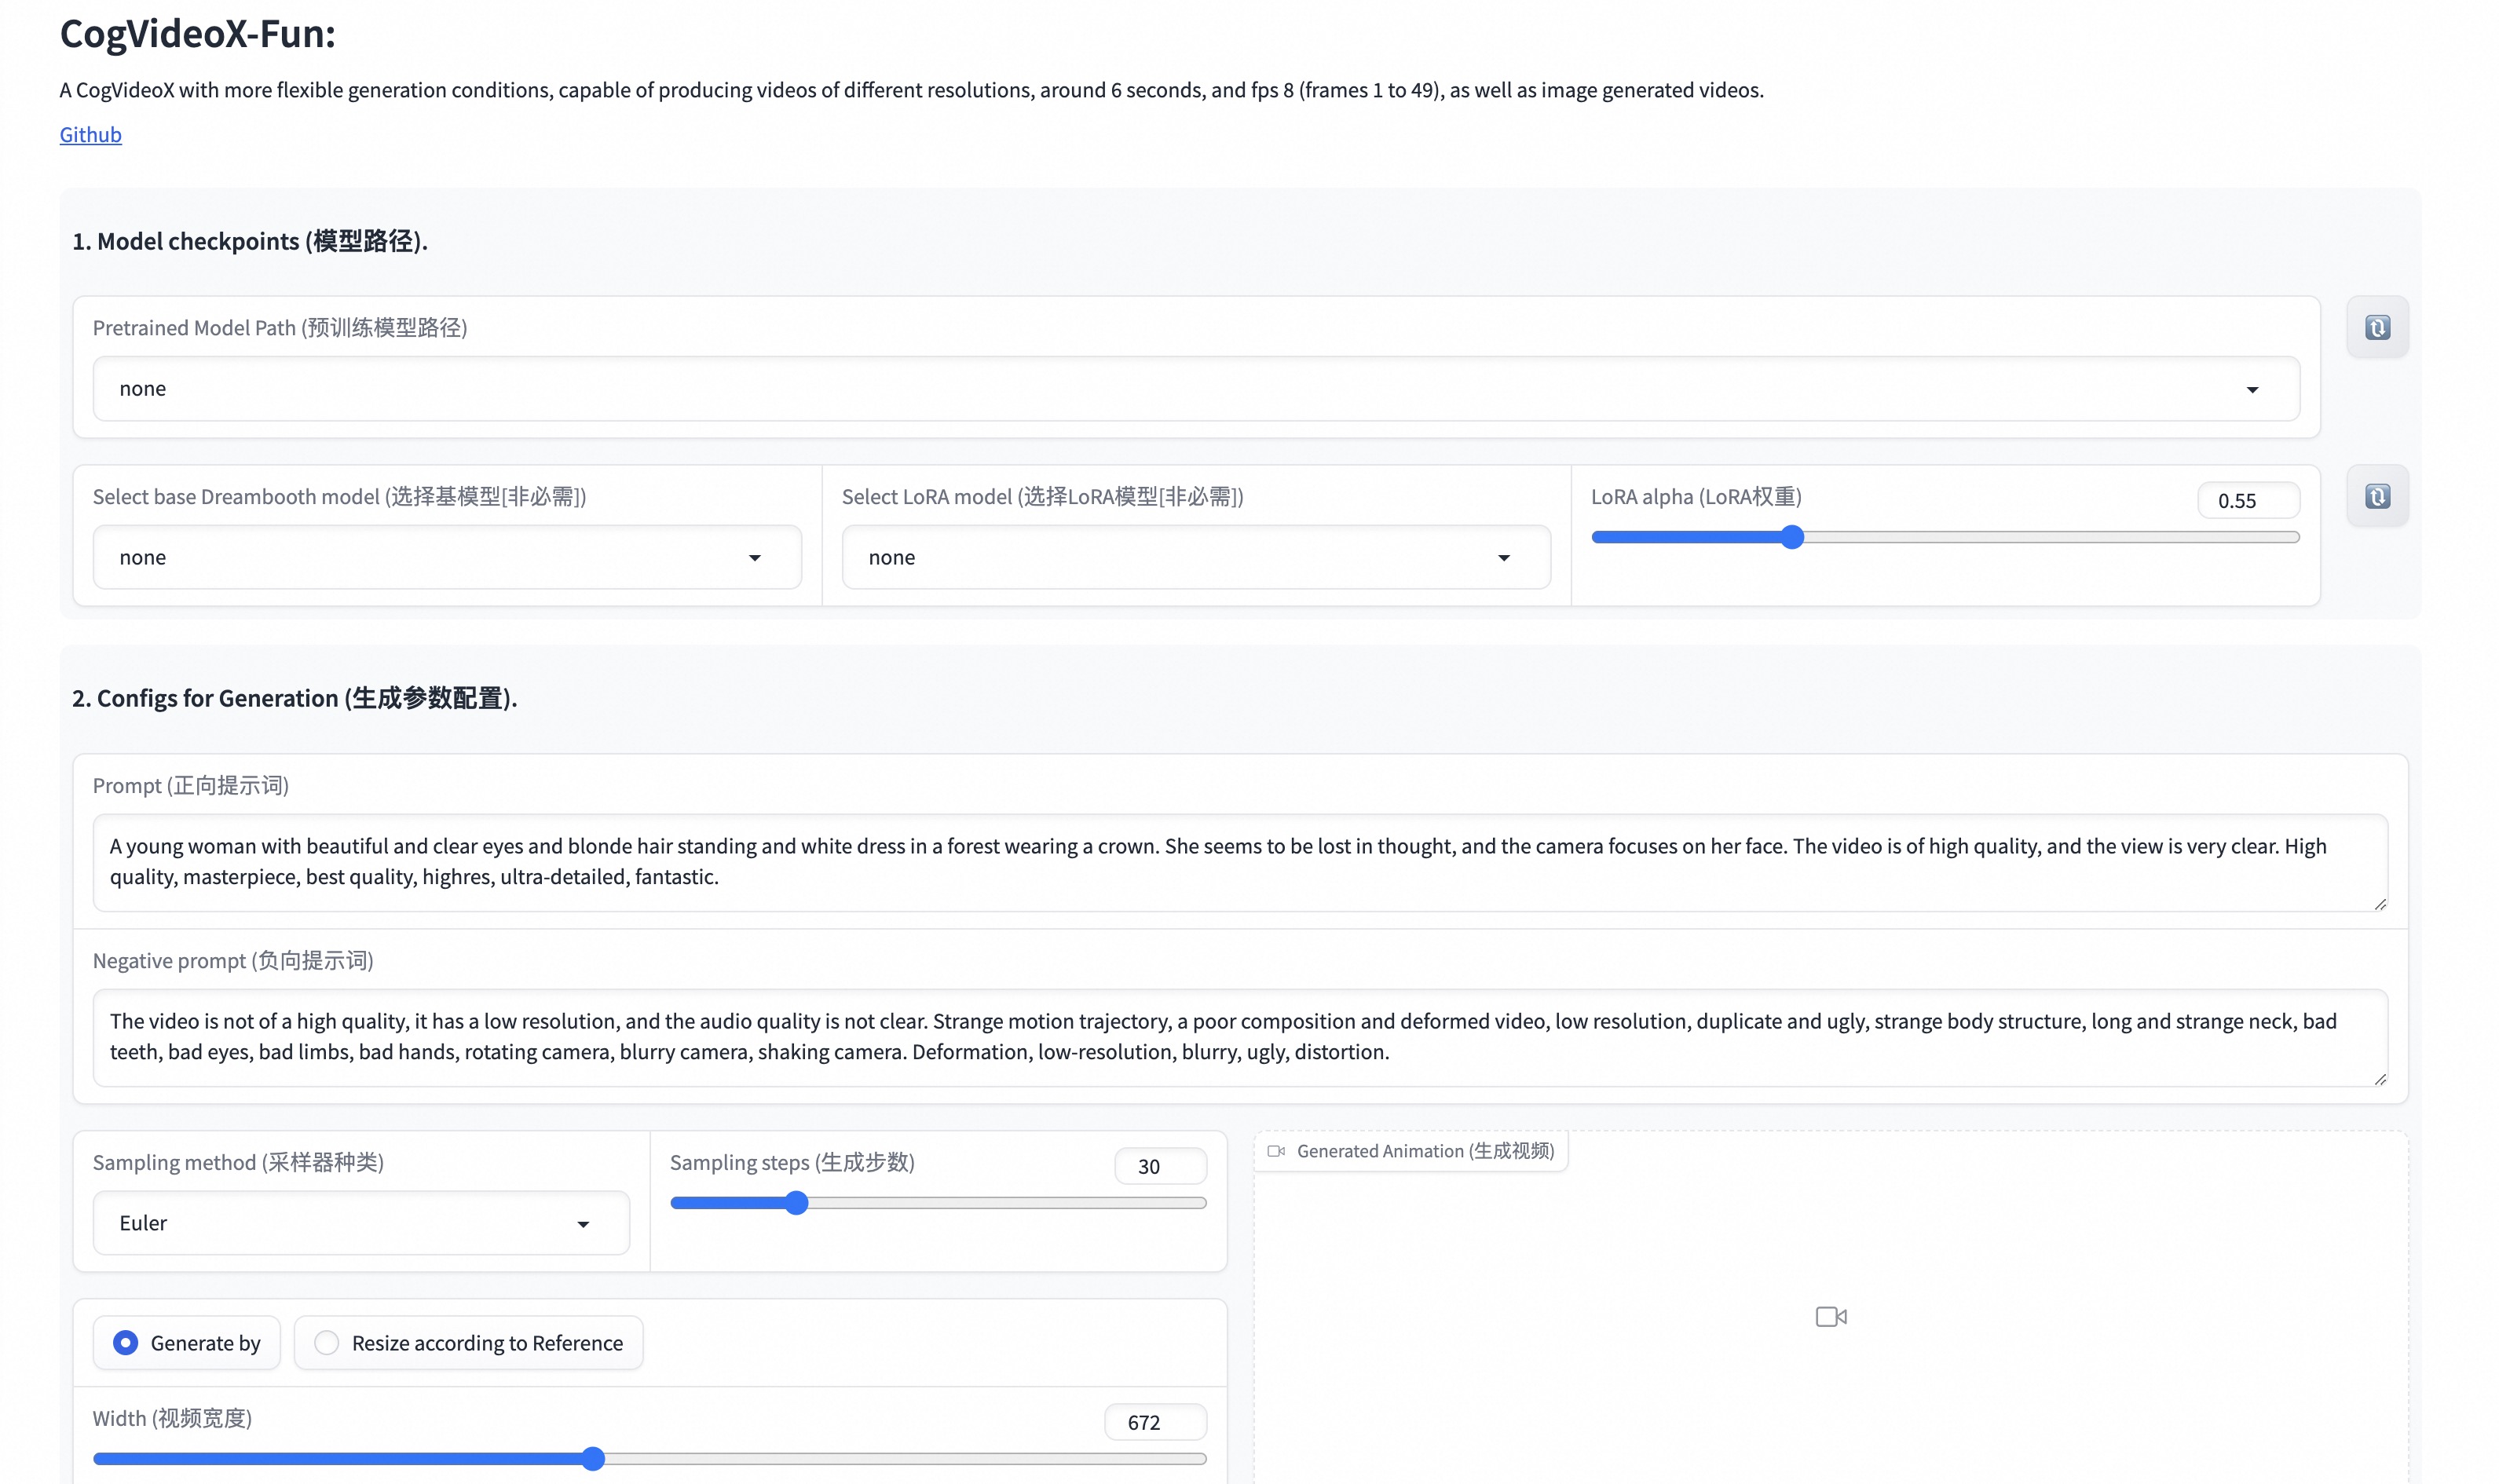
|
||||
|
||||
# II. Quick Start and Usage
|
||||
|
||||
<a id="quick-start"></a>
|
||||
@@ -302,7 +320,7 @@ For parameter details, training documents for each model are unified under `scri
|
||||
| Wan2.2-Fun | [EN](scripts/wan2.2_fun/README_TRAIN.md) / [ZH](scripts/wan2.2_fun/README_TRAIN_zh-CN.md) | [EN](scripts/wan2.2_fun/README_TRAIN_LORA.md) / [ZH](scripts/wan2.2_fun/README_TRAIN_LORA_zh-CN.md) | [Control LoRA EN](scripts/wan2.2_fun/README_TRAIN_CONTROL_LORA.md) |
|
||||
| CogVideoX-Fun | [EN](scripts/cogvideox_fun/README_TRAIN.md) / [ZH](scripts/cogvideox_fun/README_TRAIN_zh-CN.md) | [EN](scripts/cogvideox_fun/README_TRAIN_LORA.md) / [ZH](scripts/cogvideox_fun/README_TRAIN_LORA_zh-CN.md) | [Control EN](scripts/cogvideox_fun/README_TRAIN_CONTROL.md)、[Reward LoRA](scripts/cogvideox_fun/README_TRAIN_REWARD.md) |
|
||||
| Qwen-Image | [EN](scripts/qwenimage/README_TRAIN.md) / [ZH](scripts/qwenimage/README_TRAIN_zh-CN.md) | [EN](scripts/qwenimage/README_TRAIN_LORA.md) / [ZH](scripts/qwenimage/README_TRAIN_LORA_zh-CN.md) | [Edit EN](scripts/qwenimage/README_TRAIN_EDIT.md) |
|
||||
| Qwen-Image-2.1 | [EN](scripts/qwenimage21/README_TRAIN.md) / [ZH](scripts/qwenimage21/README_TRAIN_zh-CN.md) | - | [Control EN](scripts/qwenimage21_fun/README_TRAIN.md) / [ZH](scripts/qwenimage21_fun/README_TRAIN_zh-CN.md) |
|
||||
| Qwen-Image-2.1 | [EN](scripts/qwenimage21/README_TRAIN.md) / [ZH](scripts/qwenimage21/README_TRAIN_zh-CN.md) | - | - |
|
||||
| Z-Image | [EN](scripts/z_image/README_TRAIN.md) / [ZH](scripts/z_image/README_TRAIN_zh-CN.md) | [EN](scripts/z_image/README_TRAIN_LORA.md) / [ZH](scripts/z_image/README_TRAIN_LORA_zh-CN.md) | [GRPO LoRA EN](scripts/z_image/README_TRAIN_GRPO_LORA.md) |
|
||||
|
||||
For other models, check the READMEs under `scripts/{model_name}/`.
|
||||
@@ -337,7 +355,7 @@ The table below summarizes currently supported model families and weights. Video
|
||||
| Phantom | Video | Incremental weights for multi-subject reference video generation; based on Wan2.1-T2V | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">1.3B version. Officially released as .pth; place in Personalized_Model and reference via transformer_path in predict file</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">14B version. Officially released as sharded safetensors</td></tr></table> |
|
||||
| Qwen-Image | Image | Official text-to-image and image-editing weights; supports baseline and LoRA training | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image">🤖</a></td><td valign="top" style="padding:2px 0;">文生图基础权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2512">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2512">🤖</a></td><td valign="top" style="padding:2px 0;">Updated text-to-image version</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit-2509</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit-2509">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑更新版本</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Layered</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Layered">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Layered">🤖</a></td><td valign="top" style="padding:2px 0;">Image layer-decomposition weights; splits an image into multiple editable RGBA layers</td></tr></table> |
|
||||
| Qwen-Image-2.1 | Image | Official next-generation text-to-image weights; single-stream block-causal transformer with prefix KV cache | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">Single-stream block-causal transformer; supports full-parameter training, prefix KV cache speeds up inference</td></tr></table> |
|
||||
| Qwen-Image ControlNet | Image | Image controlled generation; supports Canny, Depth, Pose, MLSD, and Scribble | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for Qwen-Image-2512, supporting multiple control conditions such as Canny, Depth, Pose, MLSD, Scribble, etc.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2.1-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2.1-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet-Union weights for Qwen-Image-2.1 trained by this project, supporting control conditions such as Canny, Depth, Pose, MLSD, and image inpainting</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">Equivalent ControlNet provided by InstantX</td></tr></table> |
|
||||
| Qwen-Image ControlNet | Image | Image controlled generation; supports Canny, Depth, Pose, MLSD, and Scribble | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for Qwen-Image-2512, supporting multiple control conditions such as Canny, Depth, Pose, MLSD, Scribble, etc.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">Equivalent ControlNet provided by InstantX</td></tr></table> |
|
||||
| Z-Image | Image | Official text-to-image weights | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image">🤖</a></td><td valign="top" style="padding:2px 0;">基础版</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image-Turbo">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo">🤖</a></td><td valign="top" style="padding:2px 0;">加速版</td></tr></table> |
|
||||
| Z-Image-Fun | Image | ControlNet and distillation LoRA trained by this project on Z-Image; supports Canny, Depth, Pose, MLSD, Scribble, and Gray | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for Z-Image. Compared to the first version, it adds to more layers and has been trained for a longer period. It supports multiple control conditions including Canny, Depth, Pose, MLSD, Scribble and Gray.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for Z-Image-Turbo, supporting multiple control conditions such as Canny, Depth, Pose, MLSD, etc.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for Z-Image-Turbo. Compared to the first version, it adds to more layers and has been trained for a longer period. It supports multiple control conditions including Canny, Depth, Pose, MLSD, and more.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Lora-Distill</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill">🤖</a></td><td valign="top" style="padding:2px 0;">This is a Distill LoRA for Z-Image that distills both steps and CFG. This model does not require CFG and uses 8 steps for inference.</td></tr></table> |
|
||||
| Flux | Image | Official FLUX.1/FLUX.2 weights and the ControlNet trained by this project | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.1-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.1-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev">🤖</a></td><td valign="top" style="padding:2px 0;">文生图与图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.2-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev">🤖</a></td><td valign="top" style="padding:2px 0;">第二代官方权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for FLUX.2-dev</td></tr></table> |
|
||||
@@ -357,16 +375,16 @@ The table below summarizes currently supported model families and weights. Video
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -374,22 +392,21 @@ The table below summarizes currently supported model families and weights. Video
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
<details>
|
||||
<summary><b>Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control</b></summary>
|
||||
### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
|
||||
|
||||
Generic Control Video + Reference Image:
|
||||
|
||||
@@ -410,16 +427,16 @@ Generic Control Video + Reference Image:
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload="none"></image>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -430,13 +447,13 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -444,32 +461,29 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera</b></summary>
|
||||
### Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
@@ -485,13 +499,13 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
@@ -507,37 +521,34 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>CogVideoX-Fun-V1.1-5B</b></summary>
|
||||
### CogVideoX-Fun-V1.1-5B
|
||||
|
||||
Resolution-1024
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -548,16 +559,16 @@ Resolution-768
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -567,35 +578,32 @@ Resolution-512
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>CogVideoX-Fun-V1.1-5B-Control</b></summary>
|
||||
### CogVideoX-Fun-V1.1-5B-Control
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
@@ -611,19 +619,17 @@ Resolution-512
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
</details>
|
||||
|
||||
# V. References
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
|
||||
|
||||
+69
-63
@@ -26,6 +26,24 @@ Wan-Fun:
|
||||
# 一、紹介
|
||||
VideoX-Funはビデオ生成のパイプラインであり、AI画像やビデオの生成、Diffusion TransformerのベースラインモデルとLoraモデルのトレーニングに使用できます。我々は、すでに学習済みのベースラインモデルから直接予測を行い、異なる解像度、秒数、FPSのビデオを生成することをサポートしています。また、ユーザーが独自のベースラインモデルやLoraモデルをトレーニングし、特定のスタイル変換を行うこともサポートしています。
|
||||
|
||||
新機能:
|
||||
- Wan 2.2シリーズモデル、Wan-VACE制御モデル、Fantasy Talkingデジタルヒューマンモデル、Qwen-Image、Flux画像生成モデルなどのサポートを追加しました。[2025.10.16]
|
||||
- Wan2.1-Fun-V1.1バージョンを更新:14Bと1.3BモデルのControl+参照画像モデルをサポート、カメラ制御にも対応。さらに、Inpaintモデルを再訓練し、性能が向上しました。[2025.04.25]
|
||||
- Wan2.1-Fun-V1.0の更新:14Bおよび1.3BのI2V(画像からビデオ)モデルとControlモデルをサポートし、開始フレームと終了フレームの予測に対応。[2025.03.26]
|
||||
- CogVideoX-Fun-V1.5の更新:I2Vモデルと関連するトレーニング・予測コードをアップロード。[2024.12.16]
|
||||
- 報酬Loraのサポート:報酬逆伝播技術を使用してLoraをトレーニングし、生成された動画を最適化し、人間の好みによりよく一致させる。[詳細情報](scripts/README_TRAIN_REWARD.md)。新しいバージョンの制御モデルでは、Canny、Depth、Pose、MLSDなどの異なる制御条件に対応。[2024.11.21]
|
||||
- diffusersのサポート:CogVideoX-Fun Controlがdiffusersでサポートされるようになりました。[a-r-r-o-w](https://github.com/a-r-r-o-w)がこの[PR](https://github.com/huggingface/diffusers/pull/9671)でサポートを提供してくれたことに感謝します。詳細は[ドキュメント](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cogvideox)をご覧ください。[2024.10.16]
|
||||
- CogVideoX-Fun-V1.1の更新:i2vモデルを再トレーニングし、Noiseを追加して動画の動きの範囲を拡大。制御モデルのトレーニングコードとControlモデルをアップロード。[2024.09.29]
|
||||
- CogVideoX-Fun-V1.0の更新:コードを作成!WindowsとLinuxに対応しました。2Bおよび5Bモデルでの最大256x256x49から1024x1024x49までの任意の解像度の動画生成をサポート。[2024.09.18]
|
||||
|
||||
機能:
|
||||
- [データ前処理](#data-preprocess)
|
||||
- [DiTのトレーニング](#dit-train)
|
||||
- [ビデオ生成](#video-gen)
|
||||
|
||||
私たちのUIインターフェースは次のとおりです:
|
||||

|
||||
|
||||
# 二、クイックスタートと使用
|
||||
|
||||
<a id="quick-start"></a>
|
||||
@@ -302,7 +320,7 @@ sh scripts/{model_name}/train.sh
|
||||
| Wan2.2-Fun | [EN](scripts/wan2.2_fun/README_TRAIN.md) / [ZH](scripts/wan2.2_fun/README_TRAIN_zh-CN.md) | [EN](scripts/wan2.2_fun/README_TRAIN_LORA.md) / [ZH](scripts/wan2.2_fun/README_TRAIN_LORA_zh-CN.md) | [Control LoRA ZH](scripts/wan2.2_fun/README_TRAIN_CONTROL_LORA_zh-CN.md) |
|
||||
| CogVideoX-Fun | [EN](scripts/cogvideox_fun/README_TRAIN.md) / [ZH](scripts/cogvideox_fun/README_TRAIN_zh-CN.md) | [EN](scripts/cogvideox_fun/README_TRAIN_LORA.md) / [ZH](scripts/cogvideox_fun/README_TRAIN_LORA_zh-CN.md) | [Control ZH](scripts/cogvideox_fun/README_TRAIN_CONTROL_zh-CN.md)、[Reward LoRA](scripts/cogvideox_fun/README_TRAIN_REWARD.md) |
|
||||
| Qwen-Image | [EN](scripts/qwenimage/README_TRAIN.md) / [ZH](scripts/qwenimage/README_TRAIN_zh-CN.md) | [EN](scripts/qwenimage/README_TRAIN_LORA.md) / [ZH](scripts/qwenimage/README_TRAIN_LORA_zh-CN.md) | [Edit ZH](scripts/qwenimage/README_TRAIN_EDIT_zh-CN.md) |
|
||||
| Qwen-Image-2.1 | [EN](scripts/qwenimage21/README_TRAIN.md) / [ZH](scripts/qwenimage21/README_TRAIN_zh-CN.md) | - | [Control EN](scripts/qwenimage21_fun/README_TRAIN.md) / [ZH](scripts/qwenimage21_fun/README_TRAIN_zh-CN.md) |
|
||||
| Qwen-Image-2.1 | [EN](scripts/qwenimage21/README_TRAIN.md) / [ZH](scripts/qwenimage21/README_TRAIN_zh-CN.md) | - | - |
|
||||
| Z-Image | [EN](scripts/z_image/README_TRAIN.md) / [ZH](scripts/z_image/README_TRAIN_zh-CN.md) | [EN](scripts/z_image/README_TRAIN_LORA.md) / [ZH](scripts/z_image/README_TRAIN_LORA_zh-CN.md) | [GRPO LoRA](scripts/z_image/README_TRAIN_GRPO_LORA.md) |
|
||||
|
||||
その他のモデルも同様に、対応する`scripts/{model_name}/`下のREADMEを参照してください。
|
||||
@@ -337,7 +355,7 @@ sh scripts/{model_name}/train.sh
|
||||
| Phantom | ビデオ | 複数主体参照による動画生成の増分重み。Wan2.1-T2Vベース | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">1.3B版。公式は.pth形式で公開。Personalized_Modelに配置しpredictファイルのtransformer_pathで指定</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">14B版。公式は分割safetensors形式で公開</td></tr></table> |
|
||||
| Qwen-Image | 画像 | 公式テキストから画像生成・画像編集重み。基線とLoRA訓練をサポート | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image">🤖</a></td><td valign="top" style="padding:2px 0;">文生图基础权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2512">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2512">🤖</a></td><td valign="top" style="padding:2px 0;">テキストから画像生成の更新版</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit-2509</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit-2509">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑更新版本</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Layered</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Layered">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Layered">🤖</a></td><td valign="top" style="padding:2px 0;">画像レイヤー分解重み。画像を複数の編集可能なRGBAレイヤーに分解可能</td></tr></table> |
|
||||
| Qwen-Image-2.1 | 画像 | 公式次世代テキストから画像生成重み。シングルストリームblock-causal構造、プレフィックスKV cacheに対応 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">シングルストリームblock-causal構造。全パラメータ訓練をサポート、プレフィックスKV cacheで推論を高速化</td></tr></table> |
|
||||
| Qwen-Image ControlNet | 画像 | 画像制御生成。Canny、Depth、Pose、MLSD、Scribbleをサポート | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">Qwen-Image-2512のControlNet重み。Canny、Depth、Pose、MLSD、Scribbleなど、複数の制御条件をサポートします。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2.1-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2.1-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">本プロジェクトがQwen-Image 2.1向けに訓練したControlNet-Union。Canny、Depth、Pose、MLSDなどの制御条件と画像補完(inpaint)をサポートします。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">InstantX提供の同種ControlNet</td></tr></table> |
|
||||
| Qwen-Image ControlNet | 画像 | 画像制御生成。Canny、Depth、Pose、MLSD、Scribbleをサポート | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">Qwen-Image-2512のControlNet重み。Canny、Depth、Pose、MLSD、Scribbleなど、複数の制御条件をサポートします。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">InstantX提供の同種ControlNet</td></tr></table> |
|
||||
| Z-Image | 画像 | 公式テキストから画像生成重み | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image">🤖</a></td><td valign="top" style="padding:2px 0;">基础版</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image-Turbo">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo">🤖</a></td><td valign="top" style="padding:2px 0;">加速版</td></tr></table> |
|
||||
| Z-Image-Fun | 画像 | 本プロジェクトがZ-Imageで訓練したControlNetと蒸留LoRA。Canny、Depth、Pose、MLSD、Scribble、Grayをサポート | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">Z-ImageのControlNet重み、Canny、Depth、Pose、MLSD、ScribbleおよびGrayなど複数の制御条件に対応。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">Z-Image-Turbo用のControlNet重み。Canny、Depth、Pose、MLSDなど複数の制御条件をサポート。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">Z-Image-TurboのControlNet重み。第1版と比較して、より多くの層に追加され、より長時間トレーニングされています。Canny、Depth、Pose、MLSDなど、複数の制御条件をサポートしています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Lora-Distill</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill">🤖</a></td><td valign="top" style="padding:2px 0;">これはZ-Image用の蒸留LoRAで、ステップ数とCFGの両方を蒸留します。このモデルはCFGを必要とせず、推論には8ステップを使用します。</td></tr></table> |
|
||||
| Flux | 画像 | 公式FLUX.1/FLUX.2重みと本プロジェクトが訓練したControlNet | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.1-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.1-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev">🤖</a></td><td valign="top" style="padding:2px 0;">文生图与图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.2-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev">🤖</a></td><td valign="top" style="padding:2px 0;">第二代官方权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">FLUX.2-dev用ControlNet重み</td></tr></table> |
|
||||
@@ -357,16 +375,16 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -374,22 +392,21 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
<details>
|
||||
<summary><b>Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control</b></summary>
|
||||
### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
|
||||
|
||||
汎用制御動画 + 参照画像:
|
||||
|
||||
@@ -410,16 +427,16 @@ sh scripts/{model_name}/train.sh
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload="none"></image>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -430,13 +447,13 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -444,32 +461,29 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera</b></summary>
|
||||
### Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
@@ -485,13 +499,13 @@ sh scripts/{model_name}/train.sh
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
@@ -507,37 +521,34 @@ sh scripts/{model_name}/train.sh
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>CogVideoX-Fun-V1.1-5B</b></summary>
|
||||
### CogVideoX-Fun-V1.1-5B
|
||||
|
||||
解像度-1024
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -548,16 +559,16 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -567,35 +578,32 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>CogVideoX-Fun-V1.1-5B-Control</b></summary>
|
||||
### CogVideoX-Fun-V1.1-5B-Control
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
@@ -611,19 +619,17 @@ sh scripts/{model_name}/train.sh
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
</details>
|
||||
|
||||
# 五、参考文献
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
|
||||
|
||||
+19
-19
@@ -299,7 +299,7 @@ sh scripts/{model_name}/train.sh
|
||||
| Wan2.2-Fun | [中文](scripts/wan2.2_fun/README_TRAIN_zh-CN.md) / [EN](scripts/wan2.2_fun/README_TRAIN.md) | [中文](scripts/wan2.2_fun/README_TRAIN_LORA_zh-CN.md) / [EN](scripts/wan2.2_fun/README_TRAIN_LORA.md) | [Control LoRA 中文](scripts/wan2.2_fun/README_TRAIN_CONTROL_LORA_zh-CN.md) |
|
||||
| CogVideoX-Fun | [中文](scripts/cogvideox_fun/README_TRAIN_zh-CN.md) / [EN](scripts/cogvideox_fun/README_TRAIN.md) | [中文](scripts/cogvideox_fun/README_TRAIN_LORA_zh-CN.md) / [EN](scripts/cogvideox_fun/README_TRAIN_LORA.md) | [Control 中文](scripts/cogvideox_fun/README_TRAIN_CONTROL_zh-CN.md)、[Reward LoRA](scripts/cogvideox_fun/README_TRAIN_REWARD.md) |
|
||||
| Qwen-Image | [中文](scripts/qwenimage/README_TRAIN_zh-CN.md) / [EN](scripts/qwenimage/README_TRAIN.md) | [中文](scripts/qwenimage/README_TRAIN_LORA_zh-CN.md) / [EN](scripts/qwenimage/README_TRAIN_LORA.md) | [Edit 中文](scripts/qwenimage/README_TRAIN_EDIT_zh-CN.md) |
|
||||
| Qwen-Image-2.1 | [中文](scripts/qwenimage21/README_TRAIN_zh-CN.md) / [EN](scripts/qwenimage21/README_TRAIN.md) | - | [Control 中文](scripts/qwenimage21_fun/README_TRAIN_zh-CN.md) / [EN](scripts/qwenimage21_fun/README_TRAIN.md) |
|
||||
| Qwen-Image-2.1 | [中文](scripts/qwenimage21/README_TRAIN_zh-CN.md) / [EN](scripts/qwenimage21/README_TRAIN.md) | - | - |
|
||||
| Z-Image | [中文](scripts/z_image/README_TRAIN_zh-CN.md) / [EN](scripts/z_image/README_TRAIN.md) | [中文](scripts/z_image/README_TRAIN_LORA_zh-CN.md) / [EN](scripts/z_image/README_TRAIN_LORA.md) | [GRPO LoRA 中文](scripts/z_image/README_TRAIN_GRPO_LORA_zh-CN.md) |
|
||||
|
||||
其余模型(如HunyuanVideo、MiniMax-H3、Flux2-Fun、InfiniteTalk、LingBot等)同理,直接查看对应`scripts/{model_name}/`下的README即可。
|
||||
@@ -334,7 +334,7 @@ sh scripts/{model_name}/train.sh
|
||||
| Phantom | 视频 | 多主体参考生视频的增量权重,基于Wan2.1-T2V | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">1.3B版,官方以.pth发布,放入Personalized_Model后按预测脚本的transformer_path引用</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">14B版,官方以分片safetensors发布</td></tr></table> |
|
||||
| Qwen-Image | 图片 | 官方文生图与图像编辑权重,支持基线与LoRA训练 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image">🤖</a></td><td valign="top" style="padding:2px 0;">文生图基础权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2512">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2512">🤖</a></td><td valign="top" style="padding:2px 0;">文生图更新版本</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit-2509</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit-2509">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑更新版本</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Layered</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Layered">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Layered">🤖</a></td><td valign="top" style="padding:2px 0;">图像图层分解权重,可将图像拆分为多个可编辑的RGBA图层</td></tr></table> |
|
||||
| Qwen-Image-2.1 | 图片 | 官方新一代文生图权重,单流block-causal结构,支持前缀KV cache | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">单流block-causal结构,支持全参数训练;前缀KV cache可加速推理</td></tr></table> |
|
||||
| Qwen-Image ControlNet | 图片 | 图片控制生成,支持Canny、Depth、Pose、MLSD、Scribble | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">本项目训练的ControlNet</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2.1-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2.1-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">本项目为 Qwen-Image-2.1 训练的 ControlNet-Union,支持 Canny、Depth、Pose、MLSD 等控制条件与图像修复(inpaint)</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">InstantX提供的同类型ControlNet</td></tr></table> |
|
||||
| Qwen-Image ControlNet | 图片 | 图片控制生成,支持Canny、Depth、Pose、MLSD、Scribble | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">本项目训练的ControlNet</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">InstantX提供的同类型ControlNet</td></tr></table> |
|
||||
| Z-Image | 图片 | 官方文生图权重 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image">🤖</a></td><td valign="top" style="padding:2px 0;">基础版</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image-Turbo">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo">🤖</a></td><td valign="top" style="padding:2px 0;">加速版</td></tr></table> |
|
||||
| Z-Image-Fun | 图片 | 本项目在Z-Image上训练的ControlNet与蒸馏LoRA,控制条件支持Canny、Depth、Pose、MLSD、Scribble、Gray | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">基于基础版的ControlNet,2.1版层数更多、训练更充分</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">基于Turbo的ControlNet</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">基于Turbo的2.1版ControlNet,仓库含多精度文件</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Lora-Distill</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill">🤖</a></td><td valign="top" style="padding:2px 0;">同时蒸馏步数与CFG,推理仅需8步</td></tr></table> |
|
||||
| Flux | 图片 | 官方FLUX.1/FLUX.2权重与本项目训练的ControlNet | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.1-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.1-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev">🤖</a></td><td valign="top" style="padding:2px 0;">文生图与图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.2-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev">🤖</a></td><td valign="top" style="padding:2px 0;">第二代官方权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">本项目为FLUX.2-dev训练的ControlNet,支持Canny、Depth、Pose、MLSD等</td></tr></table> |
|
||||
@@ -354,16 +354,16 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -388,16 +388,16 @@ sh scripts/{model_name}/train.sh
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload="none"></image>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -408,13 +408,13 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
@@ -422,24 +422,24 @@ sh scripts/{model_name}/train.sh
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload="none"></video>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
@@ -1,7 +0,0 @@
|
||||
format: diffusers
|
||||
pipeline: qwenimage21
|
||||
transformer_additional_kwargs:
|
||||
# Dense control: inject a skip at every 2nd block (16 of 32 layers), matching the model's built-in
|
||||
# `control_layers=None` default. Must contain 0. Dial back (e.g. [0, 4, 8, ...]) to shrink the trainable adapter.
|
||||
control_layers: [0, 2, 4, 6, 8, 10, 12, 14, 16, 18, 20, 22, 24, 26, 28, 30]
|
||||
control_in_dim: 129
|
||||
@@ -10,9 +10,9 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.api.api import (infer_forward_api,
|
||||
update_diffusion_transformer_api)
|
||||
from videox_fun.ui.cogvideox_fun_ui import ui, ui_client, ui_host
|
||||
update_diffusion_transformer_api)
|
||||
from videox_fun.ui.controller import ddpm_scheduler_dict
|
||||
from videox_fun.ui.cogvideox_fun_ui import ui, ui_client, ui_host
|
||||
|
||||
if __name__ == "__main__":
|
||||
# Choose the ui mode
|
||||
|
||||
@@ -4,6 +4,7 @@ import sys
|
||||
import time
|
||||
|
||||
import gradio as gr
|
||||
import ray
|
||||
import torch
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -12,10 +13,9 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.api.api_multi_nodes import (MultiNodesEngine,
|
||||
multi_nodes_infer_forward_api)
|
||||
from videox_fun.ui.cogvideox_fun_ui import CogVideoXFunController
|
||||
multi_nodes_infer_forward_api)
|
||||
from videox_fun.ui.controller import flow_scheduler_dict
|
||||
|
||||
from videox_fun.ui.cogvideox_fun_ui import CogVideoXFunController
|
||||
|
||||
def main():
|
||||
parser = argparse.ArgumentParser(description='xDiT HTTP Service')
|
||||
|
||||
@@ -16,14 +16,18 @@ for project_root in project_roots:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLCogVideoX,
|
||||
CogVideoXTransformer3DModel, T5EncoderModel,
|
||||
T5Tokenizer)
|
||||
CogVideoXTransformer3DModel, T5EncoderModel,
|
||||
T5Tokenizer)
|
||||
from videox_fun.pipeline import (CogVideoXFunInpaintPipeline,
|
||||
CogVideoXFunPipeline)
|
||||
from videox_fun.utils import (apply_gpu_memory_mode, get_image_to_video_latent,
|
||||
merge_lora, save_videos_grid, unmerge_lora)
|
||||
CogVideoXFunPipeline)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8, replace_parameters_by_name,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -76,7 +80,7 @@ partial_video_length = None
|
||||
overlap_video_length = 4
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -103,7 +107,7 @@ transformer = CogVideoXTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -121,7 +125,7 @@ vae = AutoencoderKLCogVideoX.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -139,7 +143,7 @@ text_encoder = T5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Euler": EulerDiscreteScheduler,
|
||||
"Euler A": EulerAncestralDiscreteScheduler,
|
||||
"DPM++": DPMSolverMultistepScheduler,
|
||||
@@ -185,10 +189,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=[])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=[], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=[], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -300,7 +317,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -15,16 +15,20 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLCogVideoX,
|
||||
CogVideoXTransformer3DModel, T5EncoderModel,
|
||||
T5Tokenizer)
|
||||
from videox_fun.pipeline import (CogVideoXFunInpaintPipeline,
|
||||
CogVideoXFunPipeline)
|
||||
from videox_fun.utils import (apply_gpu_memory_mode, get_image_to_video_latent,
|
||||
merge_lora, save_videos_grid, unmerge_lora)
|
||||
CogVideoXTransformer3DModel, T5EncoderModel,
|
||||
T5Tokenizer)
|
||||
from videox_fun.pipeline import (CogVideoXFunPipeline,
|
||||
CogVideoXFunInpaintPipeline)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8, replace_parameters_by_name,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -73,7 +77,7 @@ video_length = 49
|
||||
fps = 8
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "A young woman with beautiful and clear eyes and blonde hair standing and white dress in a forest wearing a crown. She seems to be lost in thought, and the camera focuses on her face. The video is of high quality, and the view is very clear. High quality, masterpiece, best quality, highres, ultra-detailed, fantastic."
|
||||
negative_prompt = "The video is not of a high quality, it has a low resolution. Watermark present in each frame. The background is solid. Strange body and strange trajectory. Distortion. "
|
||||
@@ -95,7 +99,7 @@ transformer = CogVideoXTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -113,7 +117,7 @@ vae = AutoencoderKLCogVideoX.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -131,7 +135,7 @@ text_encoder = T5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Euler": EulerDiscreteScheduler,
|
||||
"Euler A": EulerAncestralDiscreteScheduler,
|
||||
"DPM++": DPMSolverMultistepScheduler,
|
||||
@@ -177,10 +181,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=[])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=[], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=[], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -239,7 +256,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -14,16 +14,20 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLCogVideoX,
|
||||
CogVideoXTransformer3DModel, T5EncoderModel,
|
||||
T5Tokenizer)
|
||||
from videox_fun.pipeline import (CogVideoXFunInpaintPipeline,
|
||||
CogVideoXFunPipeline)
|
||||
from videox_fun.utils import (apply_gpu_memory_mode, get_video_to_video_latent,
|
||||
merge_lora, save_videos_grid, unmerge_lora)
|
||||
CogVideoXTransformer3DModel, T5EncoderModel,
|
||||
T5Tokenizer)
|
||||
from videox_fun.pipeline import (CogVideoXFunPipeline,
|
||||
CogVideoXFunInpaintPipeline)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8, replace_parameters_by_name,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.utils import get_video_to_video_latent, save_videos_grid
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -71,7 +75,7 @@ video_length = 49
|
||||
fps = 8
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you are preparing to redraw the reference video, set validation_video and validation_video_mask.
|
||||
# If you do not use validation_video_mask, the entire video will be redrawn;
|
||||
@@ -102,7 +106,7 @@ transformer = CogVideoXTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -120,7 +124,7 @@ vae = AutoencoderKLCogVideoX.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -138,7 +142,7 @@ text_encoder = T5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Euler": EulerDiscreteScheduler,
|
||||
"Euler A": EulerAncestralDiscreteScheduler,
|
||||
"DPM++": DPMSolverMultistepScheduler,
|
||||
@@ -184,10 +188,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=[])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=[], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=[], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -234,7 +251,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -1,6 +1,7 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import (CogVideoXDDIMScheduler, DDIMScheduler,
|
||||
@@ -15,15 +16,20 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLCogVideoX,
|
||||
CogVideoXTransformer3DModel, T5EncoderModel,
|
||||
T5Tokenizer)
|
||||
from videox_fun.pipeline import CogVideoXFunControlPipeline
|
||||
from videox_fun.utils import (apply_gpu_memory_mode, get_video_to_video_latent,
|
||||
merge_lora, save_videos_grid, unmerge_lora)
|
||||
CogVideoXTransformer3DModel, T5EncoderModel,
|
||||
T5Tokenizer)
|
||||
from videox_fun.pipeline import (CogVideoXFunControlPipeline,
|
||||
CogVideoXFunInpaintPipeline)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8, replace_parameters_by_name,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import get_video_to_video_latent, save_videos_grid
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -71,7 +77,7 @@ video_length = 49
|
||||
fps = 8
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_video = "asset/pose.mp4"
|
||||
|
||||
@@ -96,7 +102,7 @@ transformer = CogVideoXTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -114,7 +120,7 @@ vae = AutoencoderKLCogVideoX.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -132,7 +138,7 @@ text_encoder = T5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Euler": EulerDiscreteScheduler,
|
||||
"Euler A": EulerAncestralDiscreteScheduler,
|
||||
"DPM++": DPMSolverMultistepScheduler,
|
||||
@@ -169,10 +175,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=[])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=[], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=[], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -217,7 +236,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -13,11 +13,15 @@ from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLFlux2, AutoTokenizer,
|
||||
ErnieImageTransformer2DModel, Mistral3Model)
|
||||
from videox_fun.pipeline import ErnieImagePipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -62,7 +66,7 @@ lora_path = None
|
||||
sample_size = [1728, 992]
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "1girl, black_hair, brown_eyes, earrings, freckles, grey_background, jewelry, lips, long_hair, looking_at_viewer, nose, piercing, realistic, red_lips, solo, upper_body"
|
||||
negative_prompt = "低分辨率,低画质,肢体畸形,手指畸形,画面过饱和,蜡像感,人脸无细节,过度光滑,画面具有AI感。构图混乱。文字模糊,扭曲。"
|
||||
@@ -84,7 +88,7 @@ transformer = ErnieImageTransformer2DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -102,7 +106,7 @@ vae = AutoencoderKLFlux2.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -120,7 +124,7 @@ text_encoder = Mistral3Model.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -151,10 +155,23 @@ if compile_dit:
|
||||
pipeline.transformer.layers[i] = torch.compile(pipeline.transformer.layers[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'timestep'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -184,7 +201,6 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -15,19 +15,24 @@ for project_root in project_roots:
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, CLIPModel,
|
||||
FantasyTalkingAudioEncoder,
|
||||
FantasyTalkingTransformer3DModel,
|
||||
FantasyTalkingTransformer3DModel, FantasyTalkingAudioEncoder,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import FantasyTalkingPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
merge_video_audio, save_videos_grid,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
merge_video_audio, save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -106,7 +111,7 @@ video_length = 81
|
||||
fps = 23
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None
|
||||
validation_image_start = "asset/8.png"
|
||||
@@ -135,7 +140,7 @@ transformer = FantasyTalkingTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -168,7 +173,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -201,7 +206,7 @@ audio_encoder_path = model_name_audio if model_name_audio is not None else os.pa
|
||||
audio_encoder = FantasyTalkingAudioEncoder(audio_encoder_path)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -239,10 +244,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -301,7 +321,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -13,16 +13,22 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, FlashHeadAudioEncoder,
|
||||
FlashHeadTransformer3DModel)
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
FlashHeadTransformer3DModel, FlashHeadAudioEncoder)
|
||||
from videox_fun.pipeline import FlashHeadPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_latent, merge_lora, merge_video_audio,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_latent, get_image,
|
||||
get_video_to_video_latent,
|
||||
merge_video_audio, save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -71,7 +77,7 @@ segment_frame_length = 33
|
||||
fps = 25
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# The path of the reference image
|
||||
ref_image = "asset/9.png"
|
||||
@@ -124,7 +130,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -140,7 +146,7 @@ audio_encoder = FlashHeadAudioEncoder(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -171,10 +177,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -227,7 +248,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -14,11 +14,15 @@ from videox_fun.models import (AutoencoderKL, CLIPTextModel, CLIPTokenizer,
|
||||
FluxTransformer2DModel, T5EncoderModel,
|
||||
T5TokenizerFast)
|
||||
from videox_fun.pipeline import FluxPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -63,7 +67,7 @@ lora_path = None
|
||||
sample_size = [1344, 768]
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "1girl, black_hair, brown_eyes, earrings, freckles, grey_background, jewelry, lips, long_hair, looking_at_viewer, nose, piercing, realistic, red_lips, solo, upper_body"
|
||||
negative_prompt = " "
|
||||
@@ -85,7 +89,7 @@ transformer = FluxTransformer2DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -103,7 +107,7 @@ vae = AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -128,7 +132,7 @@ text_encoder_2 = T5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -157,7 +161,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.text_model.encoder.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -165,10 +169,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'timestep'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -198,7 +215,6 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -2,7 +2,8 @@ import os
|
||||
import sys
|
||||
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
|
||||
from diffusers import (FlowMatchEulerDiscreteScheduler)
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
@@ -10,15 +11,20 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLFlux2, Flux2Transformer2DModel,
|
||||
from videox_fun.models import (AutoencoderKLFlux2,
|
||||
Mistral3ForConditionalGeneration,
|
||||
PixtralProcessor)
|
||||
PixtralProcessor, Flux2Transformer2DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Flux2Pipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -63,7 +69,7 @@ lora_path = None
|
||||
sample_size = [1344, 768]
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# Please use as detailed a prompt as possible to describe the object that needs to be generated.
|
||||
prompt = "1girl, black_hair, brown_eyes, earrings, freckles, grey_background, jewelry, lips, long_hair, looking_at_viewer, nose, piercing, realistic, red_lips, solo, upper_body"
|
||||
@@ -86,7 +92,7 @@ transformer = Flux2Transformer2DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -104,7 +110,7 @@ vae = AutoencoderKLFlux2.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -123,7 +129,7 @@ text_encoder = Mistral3ForConditionalGeneration.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -150,7 +156,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -158,10 +164,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'timestep'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -190,7 +209,6 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -1,9 +1,11 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
@@ -12,16 +14,23 @@ for project_root in project_roots:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLFlux2,
|
||||
Flux2ControlTransformer2DModel,
|
||||
Mistral3ForConditionalGeneration,
|
||||
PixtralProcessor)
|
||||
PixtralProcessor, Flux2ControlTransformer2DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Flux2ControlPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, get_image,
|
||||
get_image_latent, merge_lora, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -68,7 +77,7 @@ lora_path = None
|
||||
sample_size = [1728, 992]
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
image = None
|
||||
control_image = None
|
||||
@@ -99,7 +108,7 @@ transformer = Flux2ControlTransformer2DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -117,7 +126,7 @@ vae = AutoencoderKLFlux2.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -136,7 +145,7 @@ text_encoder = Mistral3ForConditionalGeneration.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -163,7 +172,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers, ignored_modules=[text_encoder.language_model.embed_tokens], transformer_layer_cls_to_wrap=["MistralDecoderLayer", "PixtralTransformer"])
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -171,10 +180,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'timestep'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -227,7 +249,6 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -1,9 +1,11 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
@@ -12,16 +14,23 @@ for project_root in project_roots:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLFlux2,
|
||||
Flux2ControlTransformer2DModel,
|
||||
Mistral3ForConditionalGeneration,
|
||||
PixtralProcessor)
|
||||
PixtralProcessor, Flux2ControlTransformer2DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Flux2ControlPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, get_image,
|
||||
get_image_latent, merge_lora, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -68,7 +77,7 @@ lora_path = None
|
||||
sample_size = [1728, 992]
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
image = None
|
||||
control_image = "asset/pose.jpg"
|
||||
@@ -99,7 +108,7 @@ transformer = Flux2ControlTransformer2DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -117,7 +126,7 @@ vae = AutoencoderKLFlux2.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -136,7 +145,7 @@ text_encoder = Mistral3ForConditionalGeneration.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -163,7 +172,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers, ignored_modules=[text_encoder.language_model.embed_tokens], transformer_layer_cls_to_wrap=["MistralDecoderLayer", "PixtralTransformer"])
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -171,10 +180,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'timestep'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -227,7 +249,6 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -1,9 +1,11 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
@@ -12,16 +14,23 @@ for project_root in project_roots:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLFlux2,
|
||||
Flux2ControlTransformer2DModel,
|
||||
Mistral3ForConditionalGeneration,
|
||||
PixtralProcessor)
|
||||
PixtralProcessor, Flux2ControlTransformer2DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Flux2ControlPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, get_image,
|
||||
get_image_latent, merge_lora, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -68,7 +77,7 @@ lora_path = None
|
||||
sample_size = [1728, 992]
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
image = "asset/8.png"
|
||||
control_image = "asset/pose.jpg"
|
||||
@@ -99,7 +108,7 @@ transformer = Flux2ControlTransformer2DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -117,7 +126,7 @@ vae = AutoencoderKLFlux2.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -136,7 +145,7 @@ text_encoder = Mistral3ForConditionalGeneration.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -163,7 +172,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers, ignored_modules=[text_encoder.language_model.embed_tokens], transformer_layer_cls_to_wrap=["MistralDecoderLayer", "PixtralTransformer"])
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -171,10 +180,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'timestep'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -227,7 +249,6 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -4,6 +4,8 @@ import sys
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from diffusers.utils import export_to_video
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -11,20 +13,28 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from diffusers.schedulers.scheduling_unipc_multistep import \
|
||||
UniPCMultistepScheduler
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLHunyuanVideo, CLIPImageProcessor,
|
||||
CLIPTextModel, CLIPTokenizer,
|
||||
HunyuanVideoTransformer3DModel,
|
||||
LlamaTokenizerFast,
|
||||
LlavaForConditionalGeneration)
|
||||
from videox_fun.pipeline import HunyuanVideoI2VPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, get_image, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.models import (AutoencoderKLHunyuanVideo, CLIPTextModel, CLIPImageProcessor,
|
||||
CLIPTokenizer, HunyuanVideoTransformer3DModel,
|
||||
LlavaForConditionalGeneration, LlamaTokenizerFast)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import HunyuanVideoPipeline, HunyuanVideoI2VPipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
from videox_fun.utils.utils import get_image
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -71,7 +81,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -96,7 +106,7 @@ transformer = HunyuanVideoTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -113,7 +123,7 @@ vae = AutoencoderKLHunyuanVideo.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -152,7 +162,7 @@ image_processor = CLIPImageProcessor.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -189,10 +199,23 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['x_embedder', 'context_embedder', 'time_text_embed', 'rope', 'proj_out'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["x_embedder", "context_embedder", "time_text_embed", "rope", "proj_out"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["x_embedder", "context_embedder", "time_text_embed", "rope", "proj_out"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -235,7 +258,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -4,6 +4,8 @@ import sys
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from diffusers.utils import export_to_video
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -11,18 +13,27 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from diffusers.schedulers.scheduling_unipc_multistep import \
|
||||
UniPCMultistepScheduler
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLHunyuanVideo, CLIPTextModel,
|
||||
CLIPTokenizer, HunyuanVideoTransformer3DModel,
|
||||
LlamaModel, LlamaTokenizerFast)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import HunyuanVideoPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -69,7 +80,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "1girl, black_hair, brown_eyes, earrings, freckles, grey_background, jewelry, lips, long_hair, looking_at_viewer, nose, piercing, realistic, red_lips, solo, upper_body"
|
||||
negative_prompt = "The video is not of a high quality, it has a low resolution. Watermark present in each frame. The background is solid. Strange body and strange trajectory. Distortion. "
|
||||
@@ -90,7 +101,7 @@ transformer = HunyuanVideoTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -107,7 +118,7 @@ vae = AutoencoderKLHunyuanVideo.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -141,7 +152,7 @@ text_encoder_2 = CLIPTextModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -177,10 +188,23 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['x_embedder', 'context_embedder', 'time_text_embed', 'rope', 'proj_out'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["x_embedder", "context_embedder", "time_text_embed", "rope", "proj_out"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["x_embedder", "context_embedder", "time_text_embed", "rope", "proj_out"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -219,7 +243,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -13,19 +13,25 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoTokenizer, CLIPModel,
|
||||
InfiniteTalkAudioEncoder,
|
||||
InfiniteTalkTransformer3DModel,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, CLIPModel,
|
||||
InfiniteTalkTransformer3DModel, InfiniteTalkAudioEncoder,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.pipeline import InfiniteTalkPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs, get_image,
|
||||
get_image_latent, merge_lora, merge_video_audio,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_latent, get_image,
|
||||
get_video_to_video_latent,
|
||||
merge_video_audio, save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -89,7 +95,7 @@ segment_frame_length = 81
|
||||
fps = 25
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# The path of the reference image
|
||||
ref_image = "asset/8.png"
|
||||
@@ -144,7 +150,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -180,7 +186,7 @@ clip_image_encoder = CLIPModel.from_pretrained(
|
||||
clip_image_encoder = clip_image_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -218,10 +224,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -284,7 +305,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -13,11 +13,15 @@ from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLFlux2, AutoTokenizer,
|
||||
LensGptOssEncoder, LensTransformer2DModel)
|
||||
from videox_fun.pipeline import LensPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -62,7 +66,7 @@ lora_path = None
|
||||
sample_size = [1728, 992]
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# Set to True on A100/V100 to dequantize MXFP4 GPT-OSS weights.
|
||||
dequantize_mxfp4 = False
|
||||
@@ -87,7 +91,7 @@ transformer = LensTransformer2DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -105,7 +109,7 @@ vae = AutoencoderKLFlux2.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -132,7 +136,7 @@ text_encoder = LensGptOssEncoder.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -167,10 +171,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'timestep'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -200,7 +217,6 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -18,9 +18,13 @@ from videox_fun.models import (AutoencoderKLQwenImage,
|
||||
from videox_fun.models.lingbot_video_rewriter import ensure_json_caption
|
||||
from videox_fun.pipeline import LingBotVideoI2VPipeline
|
||||
from videox_fun.pipeline.pipeline_lingbot_video import DEFAULT_NEGATIVE_PROMPT
|
||||
from videox_fun.utils import (FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import save_videos_grid
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -72,7 +76,7 @@ video_length = 81
|
||||
fps = 24
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# The condition image is used twice: as Qwen3-VL visual input and as a clean
|
||||
# first-frame latent injected into the diffusion latent (ti2v).
|
||||
@@ -104,6 +108,7 @@ prompt = ensure_json_caption(
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
|
||||
|
||||
transformer = LingBotVideoTransformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, "transformer"),
|
||||
low_cpu_mem_usage=True,
|
||||
@@ -115,7 +120,7 @@ transformer = transformer.to(weight_dtype)
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -133,7 +138,7 @@ vae = AutoencoderKLQwenImage.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -155,7 +160,7 @@ text_encoder = Qwen3VLForConditionalGeneration.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
}[sampler_name]
|
||||
scheduler = Chosen_Scheduler.from_pretrained(
|
||||
@@ -172,10 +177,21 @@ pipeline = LingBotVideoI2VPipeline(
|
||||
scheduler=scheduler,
|
||||
)
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['time_embedder', 'time_modulation', 'text_embedder', 'norm', 'router', 'scale_shift_table', 'proj_out'])
|
||||
if GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["time_embedder", "time_modulation", "text_embedder", "norm", "router", "scale_shift_table", "proj_out"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["time_embedder", "time_modulation", "text_embedder", "norm", "router", "scale_shift_table", "proj_out"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
@@ -225,7 +241,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -15,12 +15,17 @@ from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLQwenImage,
|
||||
LingBotVideoTransformer3DModel,
|
||||
Qwen3VLForConditionalGeneration)
|
||||
from videox_fun.models.lingbot_video_rewriter import ensure_json_caption
|
||||
from videox_fun.pipeline import LingBotVideoPipeline
|
||||
from videox_fun.pipeline.pipeline_lingbot_video import DEFAULT_NEGATIVE_PROMPT
|
||||
from videox_fun.utils import (FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import save_videos_grid
|
||||
|
||||
from videox_fun.models.lingbot_video_rewriter import ensure_json_caption
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -73,7 +78,7 @@ video_length = 81
|
||||
fps = 24
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# prompts
|
||||
# Write a plain natural-language prompt: it is ALWAYS rewritten into the
|
||||
@@ -106,6 +111,7 @@ prompt = ensure_json_caption(
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
|
||||
|
||||
transformer = LingBotVideoTransformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, "transformer"),
|
||||
low_cpu_mem_usage=True,
|
||||
@@ -117,7 +123,7 @@ transformer = transformer.to(weight_dtype)
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -135,7 +141,7 @@ vae = AutoencoderKLQwenImage.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -157,7 +163,7 @@ text_encoder = Qwen3VLForConditionalGeneration.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
}[sampler_name]
|
||||
scheduler = Chosen_Scheduler.from_pretrained(
|
||||
@@ -174,10 +180,21 @@ pipeline = LingBotVideoPipeline(
|
||||
scheduler=scheduler,
|
||||
)
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['time_embedder', 'time_modulation', 'text_embedder', 'norm', 'router', 'scale_shift_table', 'proj_out'])
|
||||
if GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["time_embedder", "time_modulation", "text_embedder", "norm", "router", "scale_shift_table", "proj_out"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["time_embedder", "time_modulation", "text_embedder", "norm", "router", "scale_shift_table", "proj_out"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
@@ -225,7 +242,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -15,12 +15,17 @@ from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLQwenImage,
|
||||
LingBotVideoTransformer3DModel,
|
||||
Qwen3VLForConditionalGeneration)
|
||||
from videox_fun.models.lingbot_video_rewriter import ensure_json_caption
|
||||
from videox_fun.pipeline import LingBotVideoPipeline
|
||||
from videox_fun.pipeline.pipeline_lingbot_video import (
|
||||
DEFAULT_NEGATIVE_PROMPT, prepare_refiner_latent)
|
||||
from videox_fun.utils import (FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, save_videos_grid)
|
||||
from videox_fun.pipeline.pipeline_lingbot_video import (DEFAULT_NEGATIVE_PROMPT,
|
||||
prepare_refiner_latent)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.utils import save_videos_grid
|
||||
|
||||
from videox_fun.models.lingbot_video_rewriter import ensure_json_caption
|
||||
|
||||
# Two-stage LingBot-Video t2v: the base DiT samples at a low resolution, then the
|
||||
# "refiner" DiT re-noises the upsampled latent to sigma = refiner_t_thresh and
|
||||
@@ -84,7 +89,7 @@ video_length = 81
|
||||
fps = 24
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# prompts
|
||||
# Write a plain natural-language prompt: it is ALWAYS rewritten into the
|
||||
@@ -139,7 +144,7 @@ def load_transformer(root, subpath, checkpoint_path):
|
||||
if checkpoint_path is not None:
|
||||
print(f"From checkpoint: {checkpoint_path}")
|
||||
if checkpoint_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(checkpoint_path)
|
||||
else:
|
||||
state_dict = torch.load(checkpoint_path, map_location="cpu")
|
||||
@@ -172,7 +177,7 @@ vae = AutoencoderKLQwenImage.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -187,7 +192,7 @@ processor = AutoProcessor.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
}[sampler_name]
|
||||
scheduler = Chosen_Scheduler.from_pretrained(
|
||||
@@ -226,10 +231,21 @@ pipeline = LingBotVideoPipeline(
|
||||
processor=processor,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['time_embedder', 'time_modulation', 'text_embedder', 'norm', 'router', 'scale_shift_table', 'proj_out'])
|
||||
if GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["time_embedder", "time_modulation", "text_embedder", "norm", "router", "scale_shift_table", "proj_out"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["time_embedder", "time_modulation", "text_embedder", "norm", "router", "scale_shift_table", "proj_out"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
@@ -281,12 +297,24 @@ refiner_pipeline = LingBotVideoPipeline(
|
||||
processor=processor,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(refiner_pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=["time_embedder", "time_modulation", "text_embedder", "norm", "router", "scale_shift_table", "proj_out"])
|
||||
if GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(refiner_pipeline.transformer)
|
||||
safe_enable_group_offload(refiner_pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(refiner, exclude_module_name=["time_embedder", "time_modulation", "text_embedder", "norm", "router", "scale_shift_table", "proj_out"], device=device)
|
||||
convert_weight_dtype_wrapper(refiner, weight_dtype)
|
||||
refiner_pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
refiner_pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(refiner, exclude_module_name=["time_embedder", "time_modulation", "text_embedder", "norm", "router", "scale_shift_table", "proj_out"], device=device)
|
||||
convert_weight_dtype_wrapper(refiner, weight_dtype)
|
||||
refiner_pipeline.to(device=device)
|
||||
else:
|
||||
refiner_pipeline.to(device=device)
|
||||
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
refiner.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
|
||||
@@ -12,17 +12,22 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.data.utils import prepare_lingbot_dit_cond_dict
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, WanT5EncoderModel,
|
||||
WanTransformer3DModel_LingbotWorld)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2I2VPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, save_videos_grid)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.data.utils import prepare_lingbot_dit_cond_dict
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -92,7 +97,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
|
||||
# Camera trajectory (poses.npy / intrinsics.npy) + reference image + prompt.
|
||||
@@ -132,7 +137,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -145,7 +150,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -167,7 +172,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -191,7 +196,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -235,11 +240,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -259,10 +289,10 @@ if cfg_skip_ratio is not None:
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
from videox_fun.utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
if lora_high_path is not None and transformer_2 is not None:
|
||||
from videox_fun.utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
pipeline = merge_lora(pipeline, lora_high_path, lora_high_weight, device=device, dtype=weight_dtype, sub_transformer_name="transformer_2")
|
||||
|
||||
with torch.no_grad():
|
||||
@@ -330,7 +360,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -17,10 +17,15 @@ from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
WanT5EncoderModel,
|
||||
WanTransformer3DModel_LingbotWorldFast)
|
||||
from videox_fun.pipeline import WanFunLingbotWorldFastPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.utils import filter_kwargs, save_videos_grid
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -108,7 +113,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
|
||||
# Camera trajectory (poses.npy / intrinsics.npy) + reference image + prompt.
|
||||
@@ -148,7 +153,7 @@ transformer = WanTransformer3DModel_LingbotWorldFast.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -166,7 +171,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -190,7 +195,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -233,10 +238,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
|
||||
@@ -4,6 +4,7 @@ import sys
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -12,16 +13,21 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLLongCatVideo, AutoTokenizer,
|
||||
LongCatVideoTransformer3DModel,
|
||||
UMT5EncoderModel)
|
||||
from videox_fun.models import (AutoencoderKLLongCatVideo, UMT5EncoderModel, AutoTokenizer,
|
||||
LongCatVideoTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import LongCatVideoPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, get_image_to_video_latent,
|
||||
merge_lora, save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8, replace_parameters_by_name,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -68,7 +74,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
validation_image_start = "asset/1.png"
|
||||
|
||||
@@ -92,7 +98,7 @@ transformer = LongCatVideoTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -109,7 +115,7 @@ vae = AutoencoderKLLongCatVideo.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -131,7 +137,7 @@ text_encoder = UMT5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -166,10 +172,24 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -215,7 +235,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -6,6 +6,7 @@ import numpy as np
|
||||
import torch
|
||||
from audio_separator.separator import Separator
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -18,14 +19,20 @@ from videox_fun.models import (AutoencoderKLLongCatVideo, AutoTokenizer,
|
||||
LongCatVideoAudioEncoder,
|
||||
LongCatVideoAvatarTransformer3DModel,
|
||||
UMT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import LongCatVideoAvatarPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, get_image_to_video_latent,
|
||||
merge_lora, merge_video_audio, save_videos_grid,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
merge_video_audio, save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -80,7 +87,7 @@ audio_path = "asset/talk.wav"
|
||||
use_audio_vocal_separator = False
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# Prompt
|
||||
prompt = "A young woman with long flowing purple hair stands by the seaside on a sunny day, singing. Wearing a white sleeveless dress with a navy blue bow at the collar, her hair gently sways in the ocean breeze. The sparkling sea, blue sky with white clouds, and pink wildflowers along the shore create a beautiful and vibrant scene."
|
||||
@@ -102,7 +109,7 @@ transformer = LongCatVideoAvatarTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -119,7 +126,7 @@ vae = AutoencoderKLLongCatVideo.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -147,7 +154,7 @@ audio_encoder = LongCatVideoAudioEncoder(
|
||||
audio_encoder.audio_encoder.feature_extractor._freeze_parameters()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -183,10 +190,24 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -258,7 +279,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -4,6 +4,7 @@ import sys
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -12,16 +13,21 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLLongCatVideo, AutoTokenizer,
|
||||
LongCatVideoTransformer3DModel,
|
||||
UMT5EncoderModel)
|
||||
from videox_fun.models import (AutoencoderKLLongCatVideo, UMT5EncoderModel, AutoTokenizer,
|
||||
LongCatVideoTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import LongCatVideoPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8, replace_parameters_by_name,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -68,7 +74,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# Prompt
|
||||
prompt = "1girl, black_hair, brown_eyes, earrings, freckles, grey_background, jewelry, lips, long_hair, looking_at_viewer, nose, piercing, realistic, red_lips, solo, upper_body"
|
||||
@@ -90,7 +96,7 @@ transformer = LongCatVideoTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -107,7 +113,7 @@ vae = AutoencoderKLLongCatVideo.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -129,7 +135,7 @@ text_encoder = UMT5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -165,10 +171,24 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -207,7 +227,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -11,18 +11,25 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video,
|
||||
Gemma3ForConditionalGeneration, Gemma3Processor,
|
||||
LTX2TextConnectors, LTX2VideoTransformer3DModel,
|
||||
LTX2VocoderWithBWE)
|
||||
Gemma3ForConditionalGeneration,
|
||||
GemmaTokenizerFast, LTX2TextConnectors, Gemma3Processor,
|
||||
LTX2VideoTransformer3DModel, LTX2VocoderWithBWE)
|
||||
from videox_fun.pipeline import LTX2I2VPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora,
|
||||
save_videos_with_audio_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid,
|
||||
save_videos_with_audio_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -68,7 +75,7 @@ video_length = 121
|
||||
fps = 24
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -110,7 +117,7 @@ transformer = LTX2VideoTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -129,7 +136,7 @@ vae = AutoencoderKLLTX2Video.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -211,7 +218,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype,
|
||||
module_to_wrapper=text_encoder.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -219,10 +226,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['scale_shift_table', 'audio_scale_shift_table', 'video_a2v_cross_attn_scale_shift_table', 'audio_a2v_cross_attn_scale_shift_table', ''])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["scale_shift_table", "audio_scale_shift_table", "video_a2v_cross_attn_scale_shift_table", "audio_a2v_cross_attn_scale_shift_table", ""], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["scale_shift_table", "audio_scale_shift_table", "video_a2v_cross_attn_scale_shift_table", "audio_a2v_cross_attn_scale_shift_table", ""], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -272,7 +292,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
sr = getattr(pipeline.vocoder.config, "output_sampling_rate", audio_sample_rate)
|
||||
|
||||
@@ -11,18 +11,25 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video,
|
||||
Gemma3ForConditionalGeneration, Gemma3Processor,
|
||||
LTX2TextConnectors, LTX2VideoTransformer3DModel,
|
||||
LTX2VocoderWithBWE)
|
||||
Gemma3ForConditionalGeneration,
|
||||
GemmaTokenizerFast, LTX2TextConnectors, Gemma3Processor,
|
||||
LTX2VideoTransformer3DModel, LTX2VocoderWithBWE)
|
||||
from videox_fun.pipeline import LTX2Pipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora,
|
||||
save_videos_with_audio_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid,
|
||||
save_videos_with_audio_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -68,7 +75,7 @@ video_length = 121
|
||||
fps = 24
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "A brown dog barks on a sofa, sitting on a light-colored couch in a cozy room. Behind the dog, there is a framed painting on a shelf, surrounded by pink flowers. "
|
||||
negative_prompt = "worst quality, inconsistent motion, blurry, jittery, distorted, static, low quality, artifacts"
|
||||
@@ -106,7 +113,7 @@ transformer = LTX2VideoTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -125,7 +132,7 @@ vae = AutoencoderKLLTX2Video.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -207,7 +214,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype,
|
||||
module_to_wrapper=text_encoder.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -215,10 +222,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['scale_shift_table', 'audio_scale_shift_table', 'video_a2v_cross_attn_scale_shift_table', 'audio_a2v_cross_attn_scale_shift_table', ''])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["scale_shift_table", "audio_scale_shift_table", "video_a2v_cross_attn_scale_shift_table", "audio_a2v_cross_attn_scale_shift_table", ""], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["scale_shift_table", "audio_scale_shift_table", "video_a2v_cross_attn_scale_shift_table", "audio_a2v_cross_attn_scale_shift_table", ""], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -267,7 +287,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
sr = getattr(pipeline.vocoder.config, "output_sampling_rate", audio_sample_rate)
|
||||
|
||||
@@ -11,18 +11,25 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video,
|
||||
Gemma3ForConditionalGeneration,
|
||||
GemmaTokenizerFast, LTX2TextConnectors,
|
||||
LTX2VideoTransformer3DModel, LTX2Vocoder)
|
||||
from videox_fun.pipeline import LTX2I2VPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora,
|
||||
save_videos_with_audio_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid,
|
||||
save_videos_with_audio_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -68,7 +75,7 @@ video_length = 121
|
||||
fps = 24
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -98,7 +105,7 @@ transformer = LTX2VideoTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -117,7 +124,7 @@ vae = AutoencoderKLLTX2Video.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -195,7 +202,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype,
|
||||
module_to_wrapper=text_encoder.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -203,10 +210,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['scale_shift_table', 'audio_scale_shift_table', 'video_a2v_cross_attn_scale_shift_table', 'audio_a2v_cross_attn_scale_shift_table', ''])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["scale_shift_table", "audio_scale_shift_table", "video_a2v_cross_attn_scale_shift_table", "audio_a2v_cross_attn_scale_shift_table", ""], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["scale_shift_table", "audio_scale_shift_table", "video_a2v_cross_attn_scale_shift_table", "audio_a2v_cross_attn_scale_shift_table", ""], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -248,7 +268,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
sr = getattr(pipeline.vocoder.config, "output_sampling_rate", audio_sample_rate)
|
||||
|
||||
@@ -11,19 +11,26 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video,
|
||||
Gemma3ForConditionalGeneration,
|
||||
GemmaTokenizerFast, LTX2LatentUpsamplerModel,
|
||||
LTX2TextConnectors, LTX2VideoTransformer3DModel,
|
||||
LTX2Vocoder)
|
||||
LTX2TextConnectors,
|
||||
LTX2VideoTransformer3DModel, LTX2Vocoder)
|
||||
from videox_fun.pipeline import LTX2I2VPipeline, LTX2LatentUpsamplePipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora,
|
||||
save_videos_with_audio_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid,
|
||||
save_videos_with_audio_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -72,7 +79,7 @@ fps = 24
|
||||
enable_latent_upsample = True
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -102,7 +109,7 @@ transformer = LTX2VideoTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -121,7 +128,7 @@ vae = AutoencoderKLLTX2Video.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -199,7 +206,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype,
|
||||
module_to_wrapper=text_encoder.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -207,10 +214,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['scale_shift_table', 'audio_scale_shift_table', 'video_a2v_cross_attn_scale_shift_table', 'audio_a2v_cross_attn_scale_shift_table', ''])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["scale_shift_table", "audio_scale_shift_table", "video_a2v_cross_attn_scale_shift_table", "audio_a2v_cross_attn_scale_shift_table", ""], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["scale_shift_table", "audio_scale_shift_table", "video_a2v_cross_attn_scale_shift_table", "audio_a2v_cross_attn_scale_shift_table", ""], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -293,7 +313,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
sr = getattr(pipeline.vocoder.config, "output_sampling_rate", audio_sample_rate)
|
||||
|
||||
@@ -11,18 +11,25 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video,
|
||||
Gemma3ForConditionalGeneration,
|
||||
GemmaTokenizerFast, LTX2TextConnectors,
|
||||
LTX2VideoTransformer3DModel, LTX2Vocoder)
|
||||
from videox_fun.pipeline import LTX2Pipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora,
|
||||
save_videos_with_audio_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid,
|
||||
save_videos_with_audio_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -68,7 +75,7 @@ video_length = 121
|
||||
fps = 24
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "A brown dog barks on a sofa, sitting on a light-colored couch in a cozy room. Behind the dog, there is a framed painting on a shelf, surrounded by pink flowers. "
|
||||
negative_prompt = "worst quality, inconsistent motion, blurry, jittery, distorted, static, low quality, artifacts"
|
||||
@@ -94,7 +101,7 @@ transformer = LTX2VideoTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -113,7 +120,7 @@ vae = AutoencoderKLLTX2Video.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -191,7 +198,7 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype,
|
||||
module_to_wrapper=text_encoder.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -199,10 +206,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['scale_shift_table', 'audio_scale_shift_table', 'video_a2v_cross_attn_scale_shift_table', 'audio_a2v_cross_attn_scale_shift_table', ''])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["scale_shift_table", "audio_scale_shift_table", "video_a2v_cross_attn_scale_shift_table", "audio_a2v_cross_attn_scale_shift_table", ""], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["scale_shift_table", "audio_scale_shift_table", "video_a2v_cross_attn_scale_shift_table", "audio_a2v_cross_attn_scale_shift_table", ""], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -243,7 +263,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
sr = getattr(pipeline.vocoder.config, "output_sampling_rate", audio_sample_rate)
|
||||
|
||||
@@ -1,6 +1,7 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import Image
|
||||
|
||||
@@ -16,9 +17,12 @@ from videox_fun.models import (AutoencoderKLMiniMaxH3,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor)
|
||||
from videox_fun.pipeline import MiniMaxH3Pipeline
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, apply_gpu_memory_mode,
|
||||
convert_model_weight_to_float8, merge_lora,
|
||||
save_videos_with_audio_grid, unmerge_lora)
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import save_videos_with_audio_grid
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -80,7 +84,7 @@ validation_image_start = "asset/1.png"
|
||||
validation_image_end = None
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "一只棕色的狗摇着头,坐在舒适房间里的浅色沙发上。在狗的后面,架子上有一幅镶框的画,周围是粉红色的花朵。房间里柔和温暖的灯光营造出舒适的氛围。"
|
||||
seed = 43
|
||||
@@ -119,7 +123,7 @@ if transformer_path is not None:
|
||||
)
|
||||
else:
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -155,7 +159,7 @@ vae = AutoencoderKLMiniMaxH3.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -229,14 +233,21 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
# The FP8 conversion above has already run (before the FSDP sharding, on purpose); only the dequant
|
||||
# wrapper and the memory placement are left, which is what the preconverted tag installs.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype,
|
||||
quant_tag="qfloat8_preconverted" if GPU_memory_mode.endswith("_and_qfloat8") else None,
|
||||
exclude_module_name=[])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
|
||||
@@ -11,15 +11,20 @@ for project_root in project_roots:
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLMiniMaxH3,
|
||||
AutoencoderKLMiniMaxH3Audio,
|
||||
MiniMaxH3Transformer3DModel, Qwen2TokenizerFast,
|
||||
MiniMaxH3Transformer3DModel,
|
||||
Qwen2TokenizerFast,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor)
|
||||
from videox_fun.pipeline import (MiniMaxH3AudioReference,
|
||||
MiniMaxH3ImageReference, MiniMaxH3Pipeline,
|
||||
MiniMaxH3ImageReference,
|
||||
MiniMaxH3Pipeline,
|
||||
MiniMaxH3VideoReference)
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, apply_gpu_memory_mode,
|
||||
convert_model_weight_to_float8, merge_lora,
|
||||
save_videos_with_audio_grid, unmerge_lora)
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import save_videos_with_audio_grid
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -125,7 +130,7 @@ if transformer_path is not None:
|
||||
)
|
||||
else:
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -161,7 +166,7 @@ vae = AutoencoderKLMiniMaxH3.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -235,14 +240,21 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
# The FP8 conversion above has already run (before the FSDP sharding, on purpose); only the dequant
|
||||
# wrapper and the memory placement are left, which is what the preconverted tag installs.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype,
|
||||
quant_tag="qfloat8_preconverted" if GPU_memory_mode.endswith("_and_qfloat8") else None,
|
||||
exclude_module_name=[])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -263,6 +275,7 @@ def parse_reference(entry: str):
|
||||
return MiniMaxH3AudioReference.from_file(media)
|
||||
raise ValueError(f"A reference entry must start with `image=`, `video=` or `audio=`, got {entry!r}.")
|
||||
|
||||
|
||||
# Decode every reference at the rate its container carries, which the pipeline's setup resamples onto MiniMax-H3's
|
||||
# own 24 fps and the audio VAE's sample rate.
|
||||
parsed_references = [parse_reference(entry) for entry in references]
|
||||
|
||||
@@ -1,7 +1,9 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
@@ -15,9 +17,12 @@ from videox_fun.models import (AutoencoderKLMiniMaxH3,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor)
|
||||
from videox_fun.pipeline import MiniMaxH3Pipeline
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, apply_gpu_memory_mode,
|
||||
convert_model_weight_to_float8, merge_lora,
|
||||
save_videos_with_audio_grid, unmerge_lora)
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import save_videos_with_audio_grid
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -111,7 +116,7 @@ if transformer_path is not None:
|
||||
)
|
||||
else:
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -147,7 +152,7 @@ vae = AutoencoderKLMiniMaxH3.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -221,14 +226,21 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
# The FP8 conversion above has already run (before the FSDP sharding, on purpose); only the dequant
|
||||
# wrapper and the memory placement are left, which is what the preconverted tag installs.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype,
|
||||
quant_tag="qfloat8_preconverted" if GPU_memory_mode.endswith("_and_qfloat8") else None,
|
||||
exclude_module_name=[])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
|
||||
@@ -1,7 +1,9 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
@@ -16,10 +18,14 @@ from videox_fun.models import (AutoencoderKLMiniMaxH3,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor)
|
||||
from videox_fun.pipeline import MiniMaxH3ControlPipeline
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, apply_gpu_memory_mode,
|
||||
convert_model_weight_to_float8,
|
||||
get_video_to_video_latent, merge_lora,
|
||||
save_videos_with_audio_grid, unmerge_lora)
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (get_video_to_video_latent,
|
||||
save_videos_with_audio_grid)
|
||||
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -86,7 +92,7 @@ fps = 24
|
||||
control_context_scale = 1.00
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_video = "asset/pose.mp4"
|
||||
# Inpaint inputs, only read by checkpoints trained with `--enable_inpaint` (control_in_dim widened, e.g. 49):
|
||||
@@ -140,7 +146,7 @@ transformer = MiniMaxH3ControlTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -161,7 +167,7 @@ vae = AutoencoderKLMiniMaxH3.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -237,14 +243,21 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
# The FP8 conversion above has already run (before the FSDP sharding, on purpose); only the dequant
|
||||
# wrapper and the memory placement are left, which is what the preconverted tag installs.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype,
|
||||
quant_tag="qfloat8_preconverted" if GPU_memory_mode.endswith("_and_qfloat8") else None,
|
||||
exclude_module_name=[])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
|
||||
@@ -1,7 +1,9 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
@@ -16,10 +18,14 @@ from videox_fun.models import (AutoencoderKLMiniMaxH3,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor)
|
||||
from videox_fun.pipeline import MiniMaxH3ControlPipeline
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, apply_gpu_memory_mode,
|
||||
convert_model_weight_to_float8,
|
||||
get_video_to_video_latent, merge_lora,
|
||||
save_videos_with_audio_grid, unmerge_lora)
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (get_video_to_video_latent,
|
||||
save_videos_with_audio_grid)
|
||||
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -86,7 +92,7 @@ fps = 24
|
||||
control_context_scale = 1.00
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# Path of the control (e.g. pose) video; leaving it None zeroes the control channels of the side branch. With
|
||||
# inpaint inputs given the mask then guides the run on its own (the layout training reaches when it drops the
|
||||
@@ -142,7 +148,7 @@ transformer = MiniMaxH3ControlTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -163,7 +169,7 @@ vae = AutoencoderKLMiniMaxH3.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -253,14 +259,21 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
# The FP8 conversion above has already run (before the FSDP sharding, on purpose); only the dequant
|
||||
# wrapper and the memory placement are left, which is what the preconverted tag installs.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype,
|
||||
quant_tag="qfloat8_preconverted" if GPU_memory_mode.endswith("_and_qfloat8") else None,
|
||||
exclude_module_name=[])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
|
||||
@@ -17,12 +17,17 @@ from videox_fun.models import (AutoencoderKLMOVAAudio, AutoencoderKLWan,
|
||||
UMT5EncoderModel, WanAudioTransformer3DModel,
|
||||
WanTransformer3DModel)
|
||||
from videox_fun.pipeline import MOVAPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora,
|
||||
save_videos_with_audio_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import save_videos_with_audio_grid
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -288,11 +293,31 @@ if compile_dit:
|
||||
pipeline.transformer_audio.blocks[i] = torch.compile(pipeline.transformer_audio.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(pipeline.transformer, ["modulation",], device=device)
|
||||
replace_parameters_by_name(pipeline.transformer_2, ["modulation",], device=device)
|
||||
pipeline.transformer.freqs = pipeline.transformer.freqs.to(device=device)
|
||||
pipeline.transformer_2.freqs = pipeline.transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(pipeline.transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_model_weight_to_float8(pipeline.transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
convert_weight_dtype_wrapper(pipeline.transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(pipeline.transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_model_weight_to_float8(pipeline.transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
convert_weight_dtype_wrapper(pipeline.transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -342,7 +367,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
sr = getattr(pipeline.audio_vae.config, "output_sampling_rate", audio_sample_rate)
|
||||
|
||||
@@ -18,11 +18,16 @@ from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
WanT5EncoderModel, WanTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanFunPhantomPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_latent, merge_lora, save_videos_grid,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_latent,
|
||||
save_videos_grid)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -103,7 +108,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
subject_ref_images = ["asset/ref_1.png", "asset/ref_2.png"]
|
||||
|
||||
@@ -135,7 +140,7 @@ transformer = WanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -153,7 +158,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -177,7 +182,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -213,10 +218,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -276,7 +296,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -17,11 +17,16 @@ from videox_fun.models import (AutoencoderKLQwenImage,
|
||||
QwenImageTransformer2DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import QwenImageLayeredPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import get_image
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -81,7 +86,7 @@ lora_path = None
|
||||
resolution = 640
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
image = "asset/yarn-art-pikachu.png"
|
||||
|
||||
@@ -106,7 +111,7 @@ transformer = QwenImageTransformer2DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -124,7 +129,7 @@ vae = AutoencoderKLQwenImage.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -148,7 +153,7 @@ processor = Qwen2VLProcessor.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -175,8 +180,11 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
from functools import partial
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -184,10 +192,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'timestep'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -233,7 +254,6 @@ def save_results():
|
||||
prefix = str(index).zfill(8)
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
_image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -2,7 +2,8 @@ import os
|
||||
import sys
|
||||
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
|
||||
from diffusers import (FlowMatchEulerDiscreteScheduler)
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
@@ -15,11 +16,15 @@ from videox_fun.models import (AutoencoderKLQwenImage,
|
||||
Qwen2Tokenizer, QwenImageTransformer2DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import QwenImagePipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, merge_lora, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -79,7 +84,7 @@ lora_path = None
|
||||
sample_size = [1344, 768]
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# Please use as detailed a prompt as possible to describe the object that needs to be generated.
|
||||
prompt = "1girl, black_hair, brown_eyes, earrings, freckles, grey_background, jewelry, lips, long_hair, looking_at_viewer, nose, piercing, realistic, red_lips, solo, upper_body"
|
||||
@@ -102,7 +107,7 @@ transformer = QwenImageTransformer2DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -120,7 +125,7 @@ vae = AutoencoderKLQwenImage.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -138,7 +143,7 @@ text_encoder = Qwen2_5_VLForConditionalGeneration.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -164,8 +169,10 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
from functools import partial
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -173,10 +180,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'timestep'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -217,7 +237,6 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -3,6 +3,7 @@ import sys
|
||||
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
@@ -16,12 +17,16 @@ from videox_fun.models import (AutoencoderKLQwenImage,
|
||||
QwenImageTransformer2DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import QwenImageEditPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, get_image, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import get_image
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -81,7 +86,7 @@ lora_path = None
|
||||
sample_size = [1344, 768]
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
image = "asset/8.png"
|
||||
# Please use as detailed a prompt as possible to describe the object that needs to be generated.
|
||||
@@ -105,7 +110,7 @@ transformer = QwenImageTransformer2DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -123,7 +128,7 @@ vae = AutoencoderKLQwenImage.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -147,7 +152,7 @@ processor = Qwen2VLProcessor.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -174,8 +179,11 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
from functools import partial
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -183,10 +191,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'timestep'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -232,7 +253,6 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -3,6 +3,7 @@ import sys
|
||||
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
@@ -16,12 +17,16 @@ from videox_fun.models import (AutoencoderKLQwenImage,
|
||||
QwenImageTransformer2DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import QwenImageEditPlusPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, get_image, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import get_image
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -81,7 +86,7 @@ lora_path = None
|
||||
sample_size = [1344, 768]
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
image = ["asset/8.png", "asset/ref_1.png"]
|
||||
# Please use as detailed a prompt as possible to describe the object that needs to be generated.
|
||||
@@ -105,7 +110,7 @@ transformer = QwenImageTransformer2DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -123,7 +128,7 @@ vae = AutoencoderKLQwenImage.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -147,7 +152,7 @@ processor = Qwen2VLProcessor.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -174,8 +179,11 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
from functools import partial
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -183,10 +191,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'timestep'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -232,7 +253,6 @@ def save_results():
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -2,6 +2,7 @@ import os
|
||||
import sys
|
||||
|
||||
import torch
|
||||
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -14,7 +15,11 @@ from videox_fun.models import (AutoencoderKLQwenImage21,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor, QwenImage21Transformer2DModel)
|
||||
from videox_fun.pipeline import QwenImage21Pipeline
|
||||
from videox_fun.utils import apply_gpu_memory_mode, merge_lora, unmerge_lora
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -89,7 +94,7 @@ transformer = QwenImage21Transformer2DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -107,7 +112,7 @@ vae = AutoencoderKLQwenImage21.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -150,8 +155,10 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
from functools import partial
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.model.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -159,10 +166,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'time_text_embed', 'modulation'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "time_text_embed", "modulation"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "time_text_embed", "modulation"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
for prompt in prompts:
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
@@ -194,7 +214,6 @@ for prompt in prompts:
|
||||
image_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(image_path)
|
||||
print(f"Saved image to: {image_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -1,243 +0,0 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLQwenImage21,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor,
|
||||
QwenImage21ControlTransformer2DModel)
|
||||
from videox_fun.pipeline import QwenImage21ControlPipeline
|
||||
from videox_fun.utils import (apply_gpu_memory_mode, get_image_latent,
|
||||
merge_lora, unmerge_lora)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "model_group_offload"
|
||||
# Multi GPUs config
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = False
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with the fsdp_dit and sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# Config path (control_layers / control_in_dim live here and must match the trained adapter)
|
||||
config_path = "config/qwenimage21/qwenimage21_control.yaml"
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
|
||||
# Choose the sampler. Qwen-Image 2.1 is a flow-matching model sampled with the Euler discrete scheduler.
|
||||
sampler_name = "Flow"
|
||||
|
||||
# Load pretrained model if need
|
||||
transformer_path = "models/Personalized_Model/Qwen-Image-2.1-Fun-Controlnet-Union.safetensors"
|
||||
vae_path = None
|
||||
lora_path = None
|
||||
|
||||
# Other params
|
||||
sample_size = [1728, 992]
|
||||
# Cache the text and condition-image keys/values after the first denoising step. Valid because the
|
||||
# transformer modulates those tokens from t = 0, making their activations step-independent.
|
||||
use_kv_cache = True
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_image = "asset/pose.jpg"
|
||||
inpaint_image = "asset/8.png"
|
||||
mask_image = "asset/mask.png"
|
||||
# Strength of the control/union branch. 1.0 is the value the adapter is trained to consume.
|
||||
control_context_scale = 1.0
|
||||
|
||||
# Describe what should appear inside the masked (white) region.
|
||||
prompt = "A young woman with long straight black hair in an elegant three-quarter pose, wearing a white off-shoulder top with delicate lace trim, soft studio lighting against a dark blue-grey gradient background, high-fashion portrait photography, shallow depth of field."
|
||||
negative_prompt = "低分辨率,低画质,肢体畸形,手指畸形,画面过饱和,蜡像感,人脸无细节,过度光滑,画面具有AI感。构图混乱。文字模糊,扭曲。"
|
||||
guidance_scale = 1.0
|
||||
seed = 43
|
||||
num_inference_steps = 40
|
||||
lora_weight = 1.0
|
||||
save_path = "samples/qwenimage21-inpaint-images"
|
||||
|
||||
assert ring_degree == 1, (
|
||||
"Qwen-Image 2.1 only supports Ulysses (head-parallel) sequence parallelism; ring_degree must be 1, "
|
||||
"because ring attention cannot express the block-causal mask or the prefix KV cache."
|
||||
)
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
config = OmegaConf.load(config_path)
|
||||
|
||||
# Transformer
|
||||
transformer = QwenImage21ControlTransformer2DModel.from_pretrained(
|
||||
model_name,
|
||||
subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Vae
|
||||
vae = AutoencoderKLQwenImage21.from_pretrained(
|
||||
model_name,
|
||||
subfolder="vae"
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get processor and text_encoder. Qwen-Image 2.1 encodes the prompt (and any condition images) with a
|
||||
# Qwen3-VL model, so a processor replaces the plain tokenizer used by the earlier Qwen-Image families.
|
||||
processor = Qwen3VLProcessor.from_pretrained(
|
||||
model_name, subfolder="processor"
|
||||
)
|
||||
text_encoder = Qwen3VLForConditionalGeneration.from_pretrained(
|
||||
model_name, subfolder="text_encoder", torch_dtype=weight_dtype
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
}[sampler_name]
|
||||
scheduler = Chosen_Scheduler.from_pretrained(
|
||||
model_name,
|
||||
subfolder="scheduler"
|
||||
)
|
||||
|
||||
pipeline = QwenImage21ControlPipeline(
|
||||
vae=vae,
|
||||
text_encoder=text_encoder,
|
||||
processor=processor,
|
||||
transformer=transformer,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=list(transformer.transformer_blocks) + list(transformer.control_blocks))
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=pipeline.text_encoder.model.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.transformer_blocks)):
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'time_text_embed', 'modulation'])
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
# Load the conditions through get_image_latent -- the same single-frame tensors that
|
||||
# scripts/qwenimage21_fun/train_control.py validation builds -- so the resize / normalization the model was
|
||||
# trained with is reproduced here; the pipeline only preprocesses them further and assembles
|
||||
# control_context = [control_latents(64) | mask(1) | masked-image latents(64)] = 129 ch.
|
||||
if inpaint_image is not None:
|
||||
inpaint_image_input = get_image_latent(inpaint_image, sample_size=sample_size)[:, :, 0]
|
||||
else:
|
||||
inpaint_image_input = torch.zeros([1, 3, sample_size[0], sample_size[1]])
|
||||
|
||||
# In the mask, WHITE (>= 0.5) marks the region to REGENERATE and BLACK the region to KEEP -- the convention used
|
||||
# during training. get_image_latent opens it through convert("RGB"), which also resolves palette (mode "P") PNGs
|
||||
# by their rendered grey value instead of the raw palette index (asset/mask.png: 54.6% vs 0.29% regenerate area).
|
||||
if mask_image is not None:
|
||||
mask_image_input = get_image_latent(mask_image, sample_size=sample_size)[:, :1, 0]
|
||||
else:
|
||||
mask_image_input = torch.ones([1, 1, sample_size[0], sample_size[1]]) * 255
|
||||
|
||||
if control_image is not None:
|
||||
control_image_input = get_image_latent(control_image, sample_size=sample_size)[:, :, 0]
|
||||
else:
|
||||
control_image_input = None
|
||||
|
||||
with torch.no_grad():
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
negative_prompt = negative_prompt,
|
||||
height = sample_size[0],
|
||||
width = sample_size[1],
|
||||
generator = generator,
|
||||
true_cfg_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
image = inpaint_image_input,
|
||||
mask_image = mask_image_input,
|
||||
control_image = control_image_input,
|
||||
control_context_scale = control_context_scale,
|
||||
use_kv_cache = use_kv_cache,
|
||||
).images
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
# 2.1's VAE decodes to RGBA; JPEG cannot store an alpha channel, so every preview is saved as PNG.
|
||||
image_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(image_path)
|
||||
print(f"Saved image to: {image_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
else:
|
||||
save_results()
|
||||
@@ -1,224 +0,0 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLQwenImage21,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor,
|
||||
QwenImage21ControlTransformer2DModel)
|
||||
from videox_fun.pipeline import QwenImage21ControlPipeline
|
||||
from videox_fun.utils import (apply_gpu_memory_mode, get_image_latent,
|
||||
merge_lora, unmerge_lora)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "model_group_offload"
|
||||
# Multi GPUs config
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = False
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with the fsdp_dit and sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# Config path (control_layers / control_in_dim live here and must match the trained adapter)
|
||||
config_path = "config/qwenimage21/qwenimage21_control.yaml"
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
|
||||
# Choose the sampler. Qwen-Image 2.1 is a flow-matching model sampled with the Euler discrete scheduler.
|
||||
sampler_name = "Flow"
|
||||
|
||||
# Load pretrained model if need
|
||||
transformer_path = "models/Personalized_Model/Qwen-Image-2.1-Fun-Controlnet-Union.safetensors"
|
||||
vae_path = None
|
||||
lora_path = None
|
||||
|
||||
# Other params
|
||||
sample_size = [1728, 992]
|
||||
# Cache the text and condition-image keys/values after the first denoising step. Valid because the
|
||||
# transformer modulates those tokens from t = 0, making their activations step-independent.
|
||||
use_kv_cache = True
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_image = "asset/pose.jpg"
|
||||
control_context_scale = 1.0
|
||||
|
||||
# Please use as detailed a prompt as possible to describe the object that needs to be generated.
|
||||
prompt = "画面中央是一位年轻女孩,她拥有一头令人印象深刻的亮紫色长发,发丝在海风中轻盈飘扬,营造出动感而唯美的效果。她的长发两侧各扎着黑色蝴蝶结发饰,增添了几分可爱与俏皮感。女孩身穿一袭纯白色无袖连衣裙,裙摆轻盈飘逸,与她清新的气质完美契合。她的妆容精致自然,淡粉色的唇妆和温柔的眼神流露出恬静优雅的气质。她单手叉腰,姿态自信从容,目光直视镜头,展现出既甜美又不失个性的魅力。背景是一片开阔的海景,湛蓝的海水在阳光照射下波光粼粼,闪烁着钻石般的光芒。天空呈现出清澈的蔚蓝色,点缀着几朵洁白的云朵,营造出晴朗明媚的夏日氛围。画面前景右下角可见粉紫色的小花丛和绿色植物,为整体构图增添了自然生机和色彩层次。整张照片色调明亮清新,紫色头发与白色裙装、蓝色海天形成鲜明而和谐的色彩对比。"
|
||||
negative_prompt = " "
|
||||
guidance_scale = 1.0
|
||||
seed = 43
|
||||
num_inference_steps = 40
|
||||
lora_weight = 0.55
|
||||
save_path = "samples/qwenimage21-control-images"
|
||||
|
||||
assert ring_degree == 1, (
|
||||
"Qwen-Image 2.1 only supports Ulysses (head-parallel) sequence parallelism; ring_degree must be 1, "
|
||||
"because ring attention cannot express the block-causal mask or the prefix KV cache."
|
||||
)
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
config = OmegaConf.load(config_path)
|
||||
|
||||
# Transformer
|
||||
transformer = QwenImage21ControlTransformer2DModel.from_pretrained(
|
||||
model_name,
|
||||
subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Vae
|
||||
vae = AutoencoderKLQwenImage21.from_pretrained(
|
||||
model_name,
|
||||
subfolder="vae"
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get processor and text_encoder. Qwen-Image 2.1 encodes the prompt (and any condition images) with a
|
||||
# Qwen3-VL model, so a processor replaces the plain tokenizer used by the earlier Qwen-Image families.
|
||||
processor = Qwen3VLProcessor.from_pretrained(
|
||||
model_name, subfolder="processor"
|
||||
)
|
||||
text_encoder = Qwen3VLForConditionalGeneration.from_pretrained(
|
||||
model_name, subfolder="text_encoder", torch_dtype=weight_dtype
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
}[sampler_name]
|
||||
scheduler = Chosen_Scheduler.from_pretrained(
|
||||
model_name,
|
||||
subfolder="scheduler"
|
||||
)
|
||||
|
||||
pipeline = QwenImage21ControlPipeline(
|
||||
vae=vae,
|
||||
text_encoder=text_encoder,
|
||||
processor=processor,
|
||||
transformer=transformer,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=list(transformer.transformer_blocks) + list(transformer.control_blocks))
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=pipeline.text_encoder.model.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.transformer_blocks)):
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'time_text_embed', 'modulation'])
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
# Load the control image through get_image_latent -- the same single-frame (1, 3, h, w) tensor that
|
||||
# scripts/qwenimage21_fun/train_control.py validation builds, so the resize / normalization the model was trained
|
||||
# with is reproduced here instead of relying on the pipeline's own PIL preprocessing.
|
||||
if control_image is not None:
|
||||
control_image_input = get_image_latent(control_image, sample_size=sample_size)[:, :, 0]
|
||||
else:
|
||||
control_image_input = None
|
||||
|
||||
with torch.no_grad():
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
negative_prompt = negative_prompt,
|
||||
height = sample_size[0],
|
||||
width = sample_size[1],
|
||||
generator = generator,
|
||||
true_cfg_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
control_image = control_image_input,
|
||||
control_context_scale = control_context_scale,
|
||||
use_kv_cache = use_kv_cache,
|
||||
).images
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
# 2.1's VAE decodes to RGBA; JPEG cannot store an alpha channel, so every preview is saved as PNG.
|
||||
image_path = os.path.join(save_path, prefix + f"-{control_context_scale}.png")
|
||||
image = sample[0]
|
||||
image.save(image_path)
|
||||
print(f"Saved image to: {image_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
else:
|
||||
save_results()
|
||||
@@ -17,12 +17,16 @@ from videox_fun.models import (AutoencoderKLQwenImage,
|
||||
QwenImageControlTransformer2DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import QwenImageControlPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, get_image_latent,
|
||||
merge_lora, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import get_image_latent, save_videos_grid
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -84,7 +88,7 @@ lora_path = None
|
||||
sample_size = [1728, 992]
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_image = "asset/pose.jpg"
|
||||
inpaint_image = "asset/8.png"
|
||||
@@ -151,7 +155,7 @@ text_encoder = Qwen2_5_VLForConditionalGeneration.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -177,8 +181,11 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
from functools import partial
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -186,10 +193,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'timestep'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -248,7 +268,6 @@ def save_results():
|
||||
image_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(image_path)
|
||||
print(f"Saved image to: {image_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -17,12 +17,16 @@ from videox_fun.models import (AutoencoderKLQwenImage,
|
||||
QwenImageControlTransformer2DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import QwenImageControlPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, get_image_latent,
|
||||
merge_lora, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import get_image_latent, save_videos_grid
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -84,7 +88,7 @@ lora_path = None
|
||||
sample_size = [1728, 992]
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_image = "asset/pose.jpg"
|
||||
inpaint_image = None
|
||||
@@ -151,7 +155,7 @@ text_encoder = Qwen2_5_VLForConditionalGeneration.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -177,8 +181,11 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
from functools import partial
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -186,10 +193,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'timestep'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -248,7 +268,6 @@ def save_results():
|
||||
image_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(image_path)
|
||||
print(f"Saved image to: {image_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -2,7 +2,9 @@ import os
|
||||
import sys
|
||||
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
|
||||
from omegaconf import OmegaConf
|
||||
from diffusers import (FlowMatchEulerDiscreteScheduler)
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
@@ -10,19 +12,23 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLQwenImage,
|
||||
from videox_fun.models import (AutoencoderKLQwenImage, QwenImageInstantXControlNetModel,
|
||||
Qwen2_5_VLForConditionalGeneration,
|
||||
Qwen2Tokenizer,
|
||||
QwenImageInstantXControlNetModel,
|
||||
QwenImageTransformer2DModel)
|
||||
Qwen2Tokenizer, QwenImageTransformer2DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import QwenImageControlNetPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, get_image, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent, get_image,
|
||||
get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
@@ -85,7 +91,7 @@ lora_path = None
|
||||
sample_size = [1728, 992]
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_image = "asset/pose.jpg"
|
||||
controlnet_conditioning_scale = 0.80
|
||||
@@ -166,7 +172,7 @@ text_encoder = Qwen2_5_VLForConditionalGeneration.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -193,8 +199,10 @@ if ulysses_degree > 1 or ring_degree > 1:
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
from functools import partial
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.language_model.layers)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
@@ -202,10 +210,23 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=['img_in', 'txt_in', 'timestep'])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "timestep"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -251,7 +272,6 @@ def save_results():
|
||||
image_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(image_path)
|
||||
print(f"Saved image to: {image_path}")
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
|
||||
@@ -29,7 +29,8 @@ from videox_fun.pipeline.pipeline_taomate_h3 import (
|
||||
TAOMATE_H3_VIDEO_SIGMA_SHIFT, taomate_h3_canonical_continuation_plan,
|
||||
taomate_h3_direct_5s_plan, taomate_h3_select_time_shift_sigmas,
|
||||
taomate_h3_teacher_geometry)
|
||||
from videox_fun.utils import MiniMaxH3Scheduler, apply_gpu_memory_mode
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_cpu_offload, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -168,10 +169,20 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype, exclude_module_name=[], strict=True)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load":
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
raise ValueError(
|
||||
f"`GPU_memory_mode` must be one of ['model_full_load', 'model_cpu_offload', 'model_group_offload', "
|
||||
f"'sequential_cpu_offload'], got {GPU_memory_mode}."
|
||||
)
|
||||
|
||||
|
||||
def official_audio_noise(*, video_latent_t, video_latent_h, video_latent_w, audio_latent_t, seed):
|
||||
@@ -267,6 +278,7 @@ def audio_only_step_timesteps(t_video, t_audio, *, has_reference):
|
||||
|
||||
return unique_timesteps, expand
|
||||
|
||||
|
||||
_OFFLOAD_MODES = ("model_cpu_offload", "model_group_offload", "sequential_cpu_offload")
|
||||
|
||||
|
||||
@@ -540,6 +552,7 @@ def write_teacher_artifact(output_dir, *, pipeline, request_records, request_cou
|
||||
json.dump(completion, handle, ensure_ascii=False, indent=2)
|
||||
handle.write("\n")
|
||||
|
||||
|
||||
# One continuous audio timeline 5 seconds at a time: every request after the first denoises the previous
|
||||
# request's clean tail as a frozen reference, and the captured 3/6/9 rows are the Base10 teacher artifact.
|
||||
audio_rows, request_records = generate_audio_track(
|
||||
|
||||
@@ -15,9 +15,12 @@ from videox_fun.models import (AutoencoderKLMiniMaxH3,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor)
|
||||
from videox_fun.pipeline import MiniMaxH3StreamingPipeline
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, apply_gpu_memory_mode,
|
||||
convert_model_weight_to_float8, merge_lora,
|
||||
save_videos_with_audio_grid, unmerge_lora)
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import save_videos_with_audio_grid
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -130,7 +133,7 @@ if transformer_path is not None:
|
||||
)
|
||||
else:
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -156,7 +159,7 @@ vae = AutoencoderKLMiniMaxH3.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -214,14 +217,21 @@ if compile_dit:
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
# The FP8 conversion above has already run (before the FSDP sharding, on purpose); only the dequant
|
||||
# wrapper and the memory placement are left, which is what the preconverted tag installs.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype,
|
||||
quant_tag="qfloat8_preconverted" if GPU_memory_mode.endswith("_and_qfloat8") else None,
|
||||
exclude_module_name=[])
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
# Merge LoRA through the standard entry point: `merge_lora` detects an official TaoMate-H3 adapter
|
||||
# directory and converts it to the kohya layout on the fly, and takes a kohya safetensors checkpoint
|
||||
|
||||
@@ -13,15 +13,19 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, TurboWanTransformer3DModel,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8, AutoTokenizer, CLIPModel,
|
||||
WanT5EncoderModel, TurboWanTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2I2VPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8, replace_parameters_by_name,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -85,7 +89,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -122,7 +126,7 @@ transformer_2 = TurboWanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -140,7 +144,7 @@ if transformer_path is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -168,7 +172,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -192,7 +196,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -233,11 +237,32 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(transformer)
|
||||
register_auto_device_hook(transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -289,7 +314,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -15,11 +15,18 @@ for project_root in project_roots:
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
TurboWanTransformer3DModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -81,7 +88,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "A stylish woman walks down a Tokyo street filled with warm glowing neon and animated city signage. She wears a black leather jacket, a long red dress, and black boots, and carries a black purse. She wears sunglasses and red lipstick. She walks confidently and casually. The street is damp and reflective, creating a mirror effect of the colorful lights. Many pedestrians walk about."
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
@@ -103,7 +110,7 @@ transformer = TurboWanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -129,7 +136,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -152,7 +159,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -188,10 +195,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -234,7 +256,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -10,7 +10,7 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.api.api import (infer_forward_api,
|
||||
update_diffusion_transformer_api)
|
||||
update_diffusion_transformer_api)
|
||||
from videox_fun.ui.controller import flow_scheduler_dict
|
||||
from videox_fun.ui.wan_ui import ui, ui_client, ui_host
|
||||
|
||||
|
||||
@@ -4,6 +4,7 @@ import sys
|
||||
import time
|
||||
|
||||
import gradio as gr
|
||||
import ray
|
||||
import torch
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -12,11 +13,10 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.api.api_multi_nodes import (MultiNodesEngine,
|
||||
multi_nodes_infer_forward_api)
|
||||
multi_nodes_infer_forward_api)
|
||||
from videox_fun.ui.controller import flow_scheduler_dict
|
||||
from videox_fun.ui.wan_ui import Wan_Controller
|
||||
|
||||
|
||||
def main():
|
||||
parser = argparse.ArgumentParser(description='xDiT HTTP Service')
|
||||
parser.add_argument('--world_size', type=int, default=8, help='Number of parallel workers')
|
||||
|
||||
@@ -18,11 +18,16 @@ from videox_fun.models import (AutoencoderKLWan, AutoTokenizer, CLIPModel,
|
||||
WanT5EncoderModel, WanTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanI2VPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -103,7 +108,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -130,7 +135,7 @@ transformer = WanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -148,7 +153,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -178,7 +183,7 @@ clip_image_encoder = CLIPModel.from_pretrained(
|
||||
clip_image_encoder = clip_image_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -215,10 +220,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -278,7 +298,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -15,15 +15,20 @@ for project_root in project_roots:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderTinyWan,
|
||||
AutoTokenizer, CLIPModel, WanT5EncoderModel,
|
||||
WanTransformer3DModel)
|
||||
AutoTokenizer, CLIPModel,
|
||||
WanT5EncoderModel, WanTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanI2VPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -114,7 +119,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -147,7 +152,7 @@ transformer = WanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -169,7 +174,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -203,7 +208,7 @@ clip_image_encoder = CLIPModel.from_pretrained(
|
||||
clip_image_encoder = clip_image_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -240,10 +245,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -303,7 +323,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -17,10 +17,16 @@ from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
WanT5EncoderModel, WanTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -101,7 +107,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "一只棕色的狗摇着头,坐在舒适房间里的浅色沙发上。在狗的后面,架子上有一幅镶框的画,周围是粉红色的花朵。房间里柔和温暖的灯光营造出舒适的氛围。"
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
@@ -124,7 +130,7 @@ transformer = WanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -142,7 +148,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -165,7 +171,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -201,10 +207,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -258,7 +279,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -18,10 +18,16 @@ from videox_fun.models import (AutoencoderKLWan, AutoencoderTinyWan,
|
||||
WanTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -112,7 +118,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "一只棕色的狗摇着头,坐在舒适房间里的浅色沙发上。在狗的后面,架子上有一幅镶框的画,周围是粉红色的花朵。房间里柔和温暖的灯光营造出舒适的氛围。"
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
@@ -141,7 +147,7 @@ transformer = WanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -163,7 +169,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -190,7 +196,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -226,10 +232,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -283,7 +304,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -17,10 +17,16 @@ from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
WanT5EncoderModel,
|
||||
WanTransformer3DModel_SelfForcing)
|
||||
from videox_fun.pipeline import WanSelfForcingPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -160,7 +166,7 @@ if transformer_path is not None:
|
||||
print(f"use_ema={use_ema}: resolved {_raw_transformer_path} -> {transformer_path}")
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -188,7 +194,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -211,7 +217,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -248,10 +254,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -295,7 +316,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -17,11 +17,17 @@ from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
WanT5EncoderModel,
|
||||
WanTransformer3DModel_SelfForcing)
|
||||
from videox_fun.pipeline import WanSelfForcingPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler, SegmentVideoSaver,
|
||||
StreamVideoSaver, apply_gpu_memory_mode,
|
||||
filter_kwargs, merge_lora, save_videos_grid,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid, StreamVideoSaver,
|
||||
SegmentVideoSaver)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -173,7 +179,7 @@ if transformer_path is not None:
|
||||
print(f"use_ema={use_ema}: resolved {_raw_transformer_path} -> {transformer_path}")
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -201,7 +207,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -224,7 +230,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -261,10 +267,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
# Only the main process (rank 0, or single-GPU) writes files to disk.
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
@@ -342,7 +363,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -18,11 +18,17 @@ from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
WanT5EncoderModel,
|
||||
WanTransformer3DModel_FlexForcing)
|
||||
from videox_fun.pipeline import WanFlexForcingPipeline
|
||||
from videox_fun.pipeline.pipeline_wan_flex_forcing import PAPER_CHUNK_CONFIGS
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.pipeline.pipeline_wan_flex_forcing import \
|
||||
PAPER_CHUNK_CONFIGS
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import filter_kwargs, save_videos_grid
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -72,7 +78,7 @@ shift = 5
|
||||
# Any Wan2.1 / CausVid / Self-Forcing checkpoint loads as-is: the Flex-Forcing
|
||||
# backbone inherits every parameter name and only the new `flex_kproj.*` tensors
|
||||
# are reported missing (they are identity-initialised, so step 0 is unchanged).
|
||||
transformer_path = "output_dir_wan2.1_flex_forcing_distill/checkpoint-3000/diffusion_pytorch_model.safetensors"
|
||||
transformer_path = "output_dir_wan2.1_flex_forcing_distill/checkpoint-1000/diffusion_pytorch_model.safetensors"
|
||||
vae_path = None
|
||||
lora_path = None
|
||||
|
||||
@@ -93,12 +99,6 @@ fps = 16
|
||||
# so there is no second number to keep in sync. Levels only ever
|
||||
# *add* boundaries, so a KV cache written at a coarse level stays
|
||||
# valid at a finer one.
|
||||
# "full_then_blocks" -> first denoising step runs the whole clip as one
|
||||
# bidirectional ("full") chunk, every later step is the block-major
|
||||
# Self-Forcing schedule over `num_frame_per_block`. A fixed 2-level
|
||||
# ladder - coarser than the binary pyramid, no `min_num_frame_per_
|
||||
# block` involvement; needs `num_inference_steps >= 2` for the
|
||||
# block-major steps to actually run.
|
||||
# An int instead pins a truncated pyramid of exactly that many levels; for 21
|
||||
# latent frames (= 81 pixel frames) that ladder is
|
||||
# 2 -> [[21], [11, 10]] 3 -> [[21], [11, 10], [6, 5, 5, 5]]
|
||||
@@ -109,6 +109,12 @@ denoise_mode = "pyramid"
|
||||
# 3 -> leaves stay 3-frame blocks (classic Self-Forcing granularity); the
|
||||
# ladder then converges early and later steps reuse its finest level.
|
||||
min_num_frame_per_block = 1
|
||||
# Advanced: the 3.1 partition itself can also be pinned on the pipeline call
|
||||
# (`chunk_spec = "18-3" / "ar" / "uniform:3"`); the pyramid above does not need
|
||||
# it, since it derives every level from the whole-clip level 0.
|
||||
# 3.3's K-Projection (the noise-level aligned Pi_{t<-0} of the cached clean keys)
|
||||
# is deliberately not configurable here: the model builds `diag_rank1` and applies
|
||||
# it on every call, so there is nothing left to set.
|
||||
# --- Causal backbone (inherited from Self-Forcing) -------------------------
|
||||
# `num_frame_per_block` only takes effect once the pyramid is off; the rollout
|
||||
# derives the block size from the partition itself otherwise. `context_noise`
|
||||
@@ -155,7 +161,7 @@ transformer = WanTransformer3DModel_FlexForcing.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -184,7 +190,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -207,7 +213,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -244,10 +250,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
print(f"[Flex-Forcing] denoise_mode={denoise_mode}, "
|
||||
f"min_num_frame_per_block={min_num_frame_per_block}, "
|
||||
@@ -310,7 +331,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -18,11 +18,16 @@ from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
WanT5EncoderModel,
|
||||
WanTransformer3DModel_FlexForcing)
|
||||
from videox_fun.pipeline import WanFlexForcingPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_video_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -159,7 +164,7 @@ transformer = WanTransformer3DModel_FlexForcing.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -188,7 +193,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -211,7 +216,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -248,10 +253,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
print(f"[Flex-Forcing] local_attn_size={local_attn_size}, sink_size={sink_size}, "
|
||||
f"context_noise={context_noise}")
|
||||
@@ -325,7 +345,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(image_path)
|
||||
print(f"Saved image to: {image_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + "-edited.mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -10,7 +10,7 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.api.api import (infer_forward_api,
|
||||
update_diffusion_transformer_api)
|
||||
update_diffusion_transformer_api)
|
||||
from videox_fun.ui.controller import flow_scheduler_dict
|
||||
from videox_fun.ui.wan_fun_ui import ui, ui_client, ui_host
|
||||
|
||||
|
||||
@@ -4,6 +4,7 @@ import sys
|
||||
import time
|
||||
|
||||
import gradio as gr
|
||||
import ray
|
||||
import torch
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -12,11 +13,10 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.api.api_multi_nodes import (MultiNodesEngine,
|
||||
multi_nodes_infer_forward_api)
|
||||
multi_nodes_infer_forward_api)
|
||||
from videox_fun.ui.controller import flow_scheduler_dict
|
||||
from videox_fun.ui.wan_fun_ui import Wan_Fun_Controller
|
||||
|
||||
|
||||
def main():
|
||||
parser = argparse.ArgumentParser(description='xDiT HTTP Service')
|
||||
parser.add_argument('--world_size', type=int, default=8, help='Number of parallel workers')
|
||||
|
||||
@@ -18,11 +18,16 @@ from videox_fun.models import (AutoencoderKLWan, CLIPModel, WanT5EncoderModel,
|
||||
WanTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanFunInpaintPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -103,7 +108,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -131,7 +136,7 @@ transformer = WanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -149,7 +154,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -179,7 +184,7 @@ clip_image_encoder = CLIPModel.from_pretrained(
|
||||
clip_image_encoder = clip_image_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -216,10 +221,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -279,7 +299,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -18,11 +18,16 @@ from videox_fun.models import (AutoencoderKLWan, CLIPModel, WanT5EncoderModel,
|
||||
WanTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanFunInpaintPipeline, WanFunPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -103,7 +108,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "一只棕色的狗摇着头,坐在舒适房间里的浅色沙发上。在狗的后面,架子上有一幅镶框的画,周围是粉红色的花朵。房间里柔和温暖的灯光营造出舒适的氛围。"
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
@@ -126,7 +131,7 @@ transformer = WanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -144,7 +149,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -178,7 +183,7 @@ else:
|
||||
clip_image_processor = None
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -223,10 +228,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -298,7 +318,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -18,12 +18,18 @@ from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoTokenizer, CLIPModel,
|
||||
WanT5EncoderModel, WanTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanFunControlPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_latent, get_video_to_video_latent,
|
||||
merge_lora, save_videos_grid, unmerge_lora)
|
||||
from videox_fun.pipeline import WanFunControlPipeline, WanPipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_latent,
|
||||
get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -104,7 +110,7 @@ video_length = 49
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_video = "asset/pose.mp4"
|
||||
control_camera_txt = None
|
||||
@@ -139,7 +145,7 @@ transformer = WanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -157,7 +163,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -187,7 +193,7 @@ clip_image_encoder = CLIPModel.from_pretrained(
|
||||
clip_image_encoder = clip_image_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -224,10 +230,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -308,7 +329,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -18,12 +18,19 @@ from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoTokenizer, CLIPModel,
|
||||
WanT5EncoderModel, WanTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanFunControlPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_latent, get_video_to_video_latent,
|
||||
merge_lora, save_videos_grid, unmerge_lora)
|
||||
from videox_fun.pipeline import WanFunControlPipeline, WanPipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -104,7 +111,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_video = None
|
||||
control_camera_txt = "asset/Pan_Left.txt"
|
||||
@@ -139,7 +146,7 @@ transformer = WanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -157,7 +164,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -187,7 +194,7 @@ clip_image_encoder = CLIPModel.from_pretrained(
|
||||
clip_image_encoder = clip_image_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -224,10 +231,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -308,7 +330,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -18,12 +18,19 @@ from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoTokenizer, CLIPModel,
|
||||
WanT5EncoderModel, WanTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanFunControlPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_latent, get_video_to_video_latent,
|
||||
merge_lora, save_videos_grid, unmerge_lora)
|
||||
from videox_fun.pipeline import WanFunControlPipeline, WanPipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -104,7 +111,7 @@ video_length = 49
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_video = "asset/pose.mp4"
|
||||
control_camera_txt = None
|
||||
@@ -139,7 +146,7 @@ transformer = WanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -157,7 +164,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -187,7 +194,7 @@ clip_image_encoder = CLIPModel.from_pretrained(
|
||||
clip_image_encoder = clip_image_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -224,10 +231,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -308,7 +330,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -17,10 +17,16 @@ from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
WanT5EncoderModel,
|
||||
WanTransformer3DModel_SelfForcing)
|
||||
from videox_fun.pipeline import WanSelfForcingPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -84,7 +90,7 @@ independent_first_frame = False
|
||||
context_noise = 0.0
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "A stylish woman walks down a Tokyo street filled with warm glowing neon and animated city signage. She wears a black leather jacket, a long red dress, and black boots, and carries a black purse. She wears sunglasses and red lipstick. She walks confidently and casually. The street is damp and reflective, creating a mirror effect of the colorful lights. Many pedestrians walk about."
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
@@ -111,7 +117,7 @@ transformer = WanTransformer3DModel_SelfForcing.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -134,7 +140,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -157,7 +163,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -194,10 +200,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
@@ -241,7 +262,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -18,10 +18,16 @@ from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
WanT5EncoderModel,
|
||||
WanTransformer3DModel_SelfForcing)
|
||||
from videox_fun.pipeline import WanSelfForcingPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -109,7 +115,7 @@ forcing_kv_num_frame_patch = 6 # token segments per latent frame
|
||||
forcing_kv_sim_retention_ratio = 0.33 # fraction of candidate segments kept
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompts = [
|
||||
"A stylish woman walks down a Tokyo street filled with warm glowing neon and animated city signage. She wears a black leather jacket, a long red dress, and black boots, and carries a black purse. She wears sunglasses and red lipstick. She walks confidently and casually. The street is damp and reflective, creating a mirror effect of the colorful lights. Many pedestrians walk about.",
|
||||
@@ -139,7 +145,7 @@ transformer = WanTransformer3DModel_SelfForcing.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -164,7 +170,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -187,7 +193,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -224,10 +230,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
if forcing_kv_enable:
|
||||
assert forcing_kv_head_profile is not None, \
|
||||
@@ -304,7 +325,6 @@ for prompt in prompts:
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -17,11 +17,17 @@ from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
WanT5EncoderModel,
|
||||
WanTransformer3DModel_SelfForcing)
|
||||
from videox_fun.pipeline import WanSelfForcingPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler, SegmentVideoSaver,
|
||||
StreamVideoSaver, apply_gpu_memory_mode,
|
||||
filter_kwargs, merge_lora, save_videos_grid,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid, StreamVideoSaver,
|
||||
SegmentVideoSaver)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -97,7 +103,7 @@ streaming = True
|
||||
save_mode = "segments"
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "A stylish woman walks down a Tokyo street filled with warm glowing neon and animated city signage. She wears a black leather jacket, a long red dress, and black boots, and carries a black purse. She wears sunglasses and red lipstick. She walks confidently and casually. The street is damp and reflective, creating a mirror effect of the colorful lights. Many pedestrians walk about."
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
@@ -124,7 +130,7 @@ transformer = WanTransformer3DModel_SelfForcing.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -147,7 +153,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -170,7 +176,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -207,10 +213,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
# Only the main process (rank 0, or single-GPU) writes files to disk.
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
@@ -288,7 +309,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -32,7 +32,7 @@ from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
WanT5EncoderModel,
|
||||
WanTransformer3DModel_SelfForcing)
|
||||
from videox_fun.pipeline import WanSelfForcingPipeline
|
||||
from videox_fun.utils import filter_kwargs
|
||||
from videox_fun.utils.utils import filter_kwargs
|
||||
|
||||
# Config and model path
|
||||
config_path = "config/wan2.1/wan_civitai.yaml"
|
||||
@@ -90,7 +90,7 @@ transformer = WanTransformer3DModel_SelfForcing.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
|
||||
@@ -13,17 +13,24 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.data import process_pose_file
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
VaceWanTransformer3DModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanVacePipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_latent, get_image_to_video_latent,
|
||||
get_video_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.pipeline import WanPipeline, WanVacePipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -101,7 +108,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_video = None
|
||||
start_image = "asset/1.png"
|
||||
@@ -137,7 +144,7 @@ transformer = VaceWanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -155,7 +162,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -179,7 +186,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -215,10 +222,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -286,7 +308,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -13,17 +13,24 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.data import process_pose_file
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
VaceWanTransformer3DModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanVacePipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_latent, get_image_to_video_latent,
|
||||
get_video_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.pipeline import WanPipeline, WanVacePipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -102,7 +109,7 @@ fps = 16
|
||||
vace_context_scale = 1.00
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_video = None
|
||||
start_image = None
|
||||
@@ -137,7 +144,7 @@ transformer = VaceWanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -155,7 +162,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -179,7 +186,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -215,10 +222,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -286,7 +308,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -13,17 +13,24 @@ project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dir
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.data import process_pose_file
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
VaceWanTransformer3DModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanVacePipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_latent, get_image_to_video_latent,
|
||||
get_video_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.pipeline import WanPipeline, WanVacePipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -102,7 +109,7 @@ fps = 16
|
||||
vace_context_scale = 1.00
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_video = "asset/pose.mp4"
|
||||
start_image = None
|
||||
@@ -137,7 +144,7 @@ transformer = VaceWanTransformer3DModel.from_pretrained(
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -155,7 +162,7 @@ vae = AutoencoderKLWan.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -179,7 +186,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -215,10 +222,25 @@ if compile_dit:
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -286,7 +308,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -10,7 +10,7 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.api.api import (infer_forward_api,
|
||||
update_diffusion_transformer_api)
|
||||
update_diffusion_transformer_api)
|
||||
from videox_fun.ui.controller import flow_scheduler_dict
|
||||
from videox_fun.ui.wan2_2_ui import ui, ui_client, ui_host
|
||||
|
||||
|
||||
@@ -4,6 +4,7 @@ import sys
|
||||
import time
|
||||
|
||||
import gradio as gr
|
||||
import ray
|
||||
import torch
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -12,11 +13,10 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.api.api_multi_nodes import (MultiNodesEngine,
|
||||
multi_nodes_infer_forward_api)
|
||||
multi_nodes_infer_forward_api)
|
||||
from videox_fun.ui.controller import flow_scheduler_dict
|
||||
from videox_fun.ui.wan2_2_ui import Wan2_2_Controller
|
||||
|
||||
|
||||
def main():
|
||||
parser = argparse.ArgumentParser(description='xDiT HTTP Service')
|
||||
parser.add_argument('--world_size', type=int, default=8, help='Number of parallel workers')
|
||||
|
||||
@@ -19,11 +19,18 @@ from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2AnimatePipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs, get_image,
|
||||
get_video_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -112,7 +119,7 @@ segment_frame_length = 77
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "视频中的人在做动作"
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
@@ -147,7 +154,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -160,7 +167,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -182,7 +189,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -212,7 +219,7 @@ clip_image_encoder = CLIPModel.from_pretrained(
|
||||
clip_image_encoder = clip_image_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -257,11 +264,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -348,7 +380,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -14,15 +14,20 @@ for project_root in project_roots:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel,
|
||||
WanT5EncoderModel)
|
||||
AutoTokenizer, CLIPModel,
|
||||
Wan2_2Transformer3DModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2I2VPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -105,7 +110,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -144,7 +149,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -157,7 +162,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -179,7 +184,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -203,7 +208,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -247,11 +252,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -321,7 +351,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -14,16 +14,23 @@ for project_root in project_roots:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel_S2V,
|
||||
WanAudioEncoder, WanT5EncoderModel)
|
||||
AutoTokenizer, CLIPModel,
|
||||
Wan2_2Transformer3DModel_S2V, WanAudioEncoder,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2S2VPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_latent, get_video_to_video_latent,
|
||||
merge_lora, merge_video_audio, save_videos_grid,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
merge_video_audio, save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -107,7 +114,7 @@ segment_frame_length = 80
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# The path of the pose control video
|
||||
control_video = "asset/pose.mp4"
|
||||
@@ -152,7 +159,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -165,7 +172,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -187,7 +194,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -216,7 +223,7 @@ audio_encoder = WanAudioEncoder(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -261,11 +268,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -341,7 +373,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -18,10 +18,16 @@ from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2Pipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -104,7 +110,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "一只棕色的狗摇着头,坐在舒适房间里的浅色沙发上。在狗的后面,架子上有一幅镶框的画,周围是粉红色的花朵。房间里柔和温暖的灯光营造出舒适的氛围。"
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
@@ -124,20 +130,22 @@ transformer = Wan2_2Transformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_low_noise_model_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype)
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
if config['transformer_additional_kwargs'].get('transformer_combination_type', 'single') == "moe":
|
||||
transformer_2 = Wan2_2Transformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_high_noise_model_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype)
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
else:
|
||||
transformer_2 = None
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -150,7 +158,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -166,12 +174,13 @@ Chosen_AutoencoderKL = {
|
||||
}[config['vae_kwargs'].get('vae_type', 'AutoencoderKLWan')]
|
||||
vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
|
||||
additional_kwargs=OmegaConf.to_container(config['vae_kwargs'])).to(weight_dtype)
|
||||
additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -182,17 +191,19 @@ if vae_path is not None:
|
||||
|
||||
# Get Tokenizer
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')))
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
|
||||
)
|
||||
|
||||
# Get Text encoder
|
||||
text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
|
||||
additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype)
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -210,7 +221,8 @@ pipeline = Wan2_2Pipeline(
|
||||
vae=vae,
|
||||
tokenizer=tokenizer,
|
||||
text_encoder=text_encoder,
|
||||
scheduler=scheduler)
|
||||
scheduler=scheduler,
|
||||
)
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
@@ -235,11 +247,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -282,7 +319,8 @@ with torch.no_grad():
|
||||
guidance_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
boundary = boundary,
|
||||
shift = shift).videos
|
||||
shift = shift,
|
||||
).videos
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
@@ -303,7 +341,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -18,11 +18,16 @@ from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2TI2VPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -107,7 +112,7 @@ video_length = 121
|
||||
fps = 24
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -146,7 +151,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -159,7 +164,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -181,7 +186,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -204,7 +209,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -248,11 +253,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -325,7 +355,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -13,16 +13,21 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoencoderTinyWan, AutoTokenizer,
|
||||
Wan2_2Transformer3DModel, WanT5EncoderModel)
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8, AutoencoderTinyWan,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2TI2VPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -111,7 +116,7 @@ video_length = 81
|
||||
fps = 24
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -156,7 +161,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -169,7 +174,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -192,7 +197,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -221,7 +226,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -265,11 +270,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -342,7 +372,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -10,7 +10,7 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.api.api import (infer_forward_api,
|
||||
update_diffusion_transformer_api)
|
||||
update_diffusion_transformer_api)
|
||||
from videox_fun.ui.controller import flow_scheduler_dict
|
||||
from videox_fun.ui.wan2_2_fun_ui import ui, ui_client, ui_host
|
||||
|
||||
|
||||
@@ -4,6 +4,7 @@ import sys
|
||||
import time
|
||||
|
||||
import gradio as gr
|
||||
import ray
|
||||
import torch
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -12,11 +13,10 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.api.api_multi_nodes import (MultiNodesEngine,
|
||||
multi_nodes_infer_forward_api)
|
||||
multi_nodes_infer_forward_api)
|
||||
from videox_fun.ui.controller import flow_scheduler_dict
|
||||
from videox_fun.ui.wan2_2_fun_ui import Wan2_2_Fun_Controller
|
||||
|
||||
|
||||
def main():
|
||||
parser = argparse.ArgumentParser(description='xDiT HTTP Service')
|
||||
parser.add_argument('--world_size', type=int, default=8, help='Number of parallel workers')
|
||||
|
||||
@@ -14,15 +14,20 @@ for project_root in project_roots:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel,
|
||||
WanT5EncoderModel)
|
||||
AutoTokenizer, CLIPModel,
|
||||
Wan2_2Transformer3DModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2FunInpaintPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -106,7 +111,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -147,7 +152,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -160,7 +165,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -182,7 +187,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -206,7 +211,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -250,11 +255,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -324,7 +354,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -14,16 +14,21 @@ for project_root in project_roots:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel,
|
||||
AutoTokenizer, CLIPModel,
|
||||
Wan2_2Transformer3DModel,
|
||||
WanLatentUpsamplerModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import (Wan2_2FunInpaintPipeline,
|
||||
WanLatentUpsamplePipeline)
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.pipeline import Wan2_2FunInpaintPipeline, WanLatentUpsamplePipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -109,7 +114,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -150,7 +155,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -163,7 +168,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -185,7 +190,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -209,7 +214,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -253,11 +258,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -373,7 +403,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -13,18 +13,22 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoencoderTinyWan, AutoTokenizer,
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8, AutoencoderTinyWan,
|
||||
AutoTokenizer, CLIPModel,
|
||||
Wan2_2Transformer3DModel,
|
||||
WanLatentUpsamplerModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import (Wan2_2FunInpaintPipeline,
|
||||
WanLatentUpsamplePipeline)
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.pipeline import Wan2_2FunInpaintPipeline, WanLatentUpsamplePipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -113,7 +117,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -160,7 +164,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -173,7 +177,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -196,7 +200,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -224,7 +228,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -268,11 +272,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -388,7 +417,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -14,15 +14,20 @@ for project_root in project_roots:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel,
|
||||
WanT5EncoderModel)
|
||||
AutoTokenizer, CLIPModel,
|
||||
Wan2_2Transformer3DModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2FunInpaintPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -108,7 +113,7 @@ video_length = 121
|
||||
fps = 24
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
@@ -149,7 +154,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -162,7 +167,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -184,7 +189,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -208,7 +213,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -252,11 +257,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -326,7 +356,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -14,15 +14,20 @@ for project_root in project_roots:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel,
|
||||
WanT5EncoderModel)
|
||||
AutoTokenizer, CLIPModel,
|
||||
Wan2_2Transformer3DModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2FunInpaintPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -106,7 +111,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# 使用更长的neg prompt如"模糊,突变,变形,失真,画面暗,文本字幕,画面固定,连环画,漫画,线稿,没有主体。",可以增加稳定性
|
||||
# 在neg prompt中添加"安静,固定"等词语可以增加动态性。
|
||||
@@ -143,7 +148,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -156,7 +161,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -178,7 +183,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -202,7 +207,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -246,11 +251,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -320,7 +350,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -15,13 +15,20 @@ for project_root in project_roots:
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel,
|
||||
WanLatentUpsamplerModel, WanT5EncoderModel)
|
||||
WanLatentUpsamplerModel,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2Pipeline, WanLatentUpsamplePipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -107,7 +114,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# 使用更长的neg prompt如"模糊,突变,变形,失真,画面暗,文本字幕,画面固定,连环画,漫画,线稿,没有主体。",可以增加稳定性
|
||||
# 在neg prompt中添加"安静,固定"等词语可以增加动态性。
|
||||
@@ -144,7 +151,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -157,7 +164,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -179,7 +186,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -203,7 +210,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -247,11 +254,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -362,7 +394,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -13,16 +13,22 @@ for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoencoderTinyWan, AutoTokenizer,
|
||||
Wan2_2Transformer3DModel,
|
||||
WanLatentUpsamplerModel, WanT5EncoderModel)
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8, AutoencoderTinyWan,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel,
|
||||
WanLatentUpsamplerModel,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2Pipeline, WanLatentUpsamplePipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -112,7 +118,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# 使用更长的neg prompt如"模糊,突变,变形,失真,画面暗,文本字幕,画面固定,连环画,漫画,线稿,没有主体。",可以增加稳定性
|
||||
# 在neg prompt中添加"安静,固定"等词语可以增加动态性。
|
||||
@@ -155,7 +161,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -168,7 +174,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -191,7 +197,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -219,7 +225,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -263,11 +269,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -378,7 +409,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -14,15 +14,20 @@ for project_root in project_roots:
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel,
|
||||
WanT5EncoderModel)
|
||||
AutoTokenizer, CLIPModel,
|
||||
Wan2_2Transformer3DModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2FunInpaintPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -106,7 +111,7 @@ video_length = 121
|
||||
fps = 21
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# 使用更长的neg prompt如"模糊,突变,变形,失真,画面暗,文本字幕,画面固定,连环画,漫画,线稿,没有主体。",可以增加稳定性
|
||||
# 在neg prompt中添加"安静,固定"等词语可以增加动态性。
|
||||
@@ -143,7 +148,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -156,7 +161,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -178,7 +183,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -202,7 +207,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -246,11 +251,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -320,7 +350,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -16,16 +16,22 @@ for project_root in project_roots:
|
||||
from videox_fun.data import process_pose_file
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel,
|
||||
WanT5EncoderModel)
|
||||
AutoTokenizer, CLIPModel,
|
||||
Wan2_2Transformer3DModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2FunControlPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_latent, get_image_to_video_latent,
|
||||
get_video_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.pipeline import Wan2_2FunControlPipeline, WanPipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -111,7 +117,7 @@ video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_video = "asset/pose.mp4"
|
||||
control_camera_txt = None
|
||||
@@ -159,7 +165,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -172,7 +178,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -194,7 +200,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -218,7 +224,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -262,11 +268,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -350,7 +381,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
@@ -16,16 +16,22 @@ for project_root in project_roots:
|
||||
from videox_fun.data import process_pose_file
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel,
|
||||
WanT5EncoderModel)
|
||||
AutoTokenizer, CLIPModel,
|
||||
Wan2_2Transformer3DModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2FunControlPipeline
|
||||
from videox_fun.utils import (FlowDPMSolverMultistepScheduler,
|
||||
FlowUniPCMultistepScheduler,
|
||||
apply_gpu_memory_mode, filter_kwargs,
|
||||
get_image_latent, get_image_to_video_latent,
|
||||
get_video_to_video_latent, merge_lora,
|
||||
save_videos_grid, unmerge_lora)
|
||||
from videox_fun.pipeline import Wan2_2FunControlPipeline, WanPipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
@@ -111,7 +117,7 @@ video_length = 121
|
||||
fps = 24
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
control_video = "asset/pose.mp4"
|
||||
control_camera_txt = None
|
||||
@@ -159,7 +165,7 @@ else:
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
@@ -172,7 +178,7 @@ if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
@@ -194,7 +200,7 @@ vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
@@ -218,7 +224,7 @@ text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
@@ -262,11 +268,36 @@ if compile_dit:
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
# Quantize (when the mode carries an "_and_<quant>" suffix) and then place the pipeline.
|
||||
# The order lives inside the helper: quantization has to happen before the offload hooks
|
||||
# are installed, and both transformers of this MoE setup are handled in one call, which
|
||||
# is exactly the bookkeeping the old 30-line if/elif chain repeated per script.
|
||||
apply_gpu_memory_mode(pipeline, GPU_memory_mode, device, weight_dtype)
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
@@ -350,7 +381,6 @@ def save_results():
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
print(f"Saved image to: {video_path}")
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user