Compare commits
4
Commits
speed
...
README_Bug
| Author | SHA1 | Date | |
|---|---|---|---|
 bubbliiiing |
a28de73185 | ||
|
bubbliiiing
|
f537e5d2c6 | ||
|
bubbliiiing
|
50d177d8f9 | ||
|
Bubbliiiing
|
2beb171099 |
@@ -11,21 +11,21 @@ Wan-Fun:
|
||||
English | [简体中文](./README_zh-CN.md) | [日本語](./README_ja-JP.md)
|
||||
|
||||
# Table of Contents
|
||||
- [Introduction](#introduction)
|
||||
- [Quick Start](#quick-start)
|
||||
- [Video Result](#video-result)
|
||||
- [How to Use](#how-to-use)
|
||||
- [Model zoo](#model-zoo)
|
||||
- [Reference](#reference)
|
||||
- [Citation](#citation)
|
||||
- [Limitations and Risks](#limitations-and-risks)
|
||||
- [License](#license)
|
||||
- [I. Introduction](#i-introduction)
|
||||
- [II. Quick Start and Usage](#ii-quick-start-and-usage)
|
||||
- [1. Environment Preparation](#1-environment-preparation)
|
||||
- [2. Inference Generation](#2-inference-generation)
|
||||
- [3. Model Training](#3-model-training)
|
||||
- [III. Supported Models](#iii-supported-models)
|
||||
- [IV. Video Works](#iv-video-works)
|
||||
- [V. References](#v-references)
|
||||
- [VI. Citation](#vi-citation)
|
||||
- [VII. Limitations and Risks](#vii-limitations-and-risks)
|
||||
- [VIII. License](#viii-license)
|
||||
|
||||
# Introduction
|
||||
# I. Introduction
|
||||
VideoX-Fun is a video generation pipeline that can be used to generate AI images and videos, as well as to train baseline and Lora models for Diffusion Transformer. We support direct prediction from pre-trained baseline models to generate videos with different resolutions, durations, and FPS. Additionally, we also support users in training their own baseline and Lora models to perform specific style transformations.
|
||||
|
||||
We will support quick pull-ups from different platforms, refer to [Quick Start](#quick-start).
|
||||
|
||||
What's New:
|
||||
- Added support for Wan 2.2 series models, Wan-VACE control model, Fantasy Talking digital human model, Qwen-Image, Flux image generation models, and more. [2025.10.16]
|
||||
- Update Wan2.1-Fun-V1.1: Support for 14B and 1.3B model Control + Reference Image models, support for camera control, and the Inpaint model has been retrained for improved performance. [2025.04.25]
|
||||
@@ -44,20 +44,44 @@ Function:
|
||||
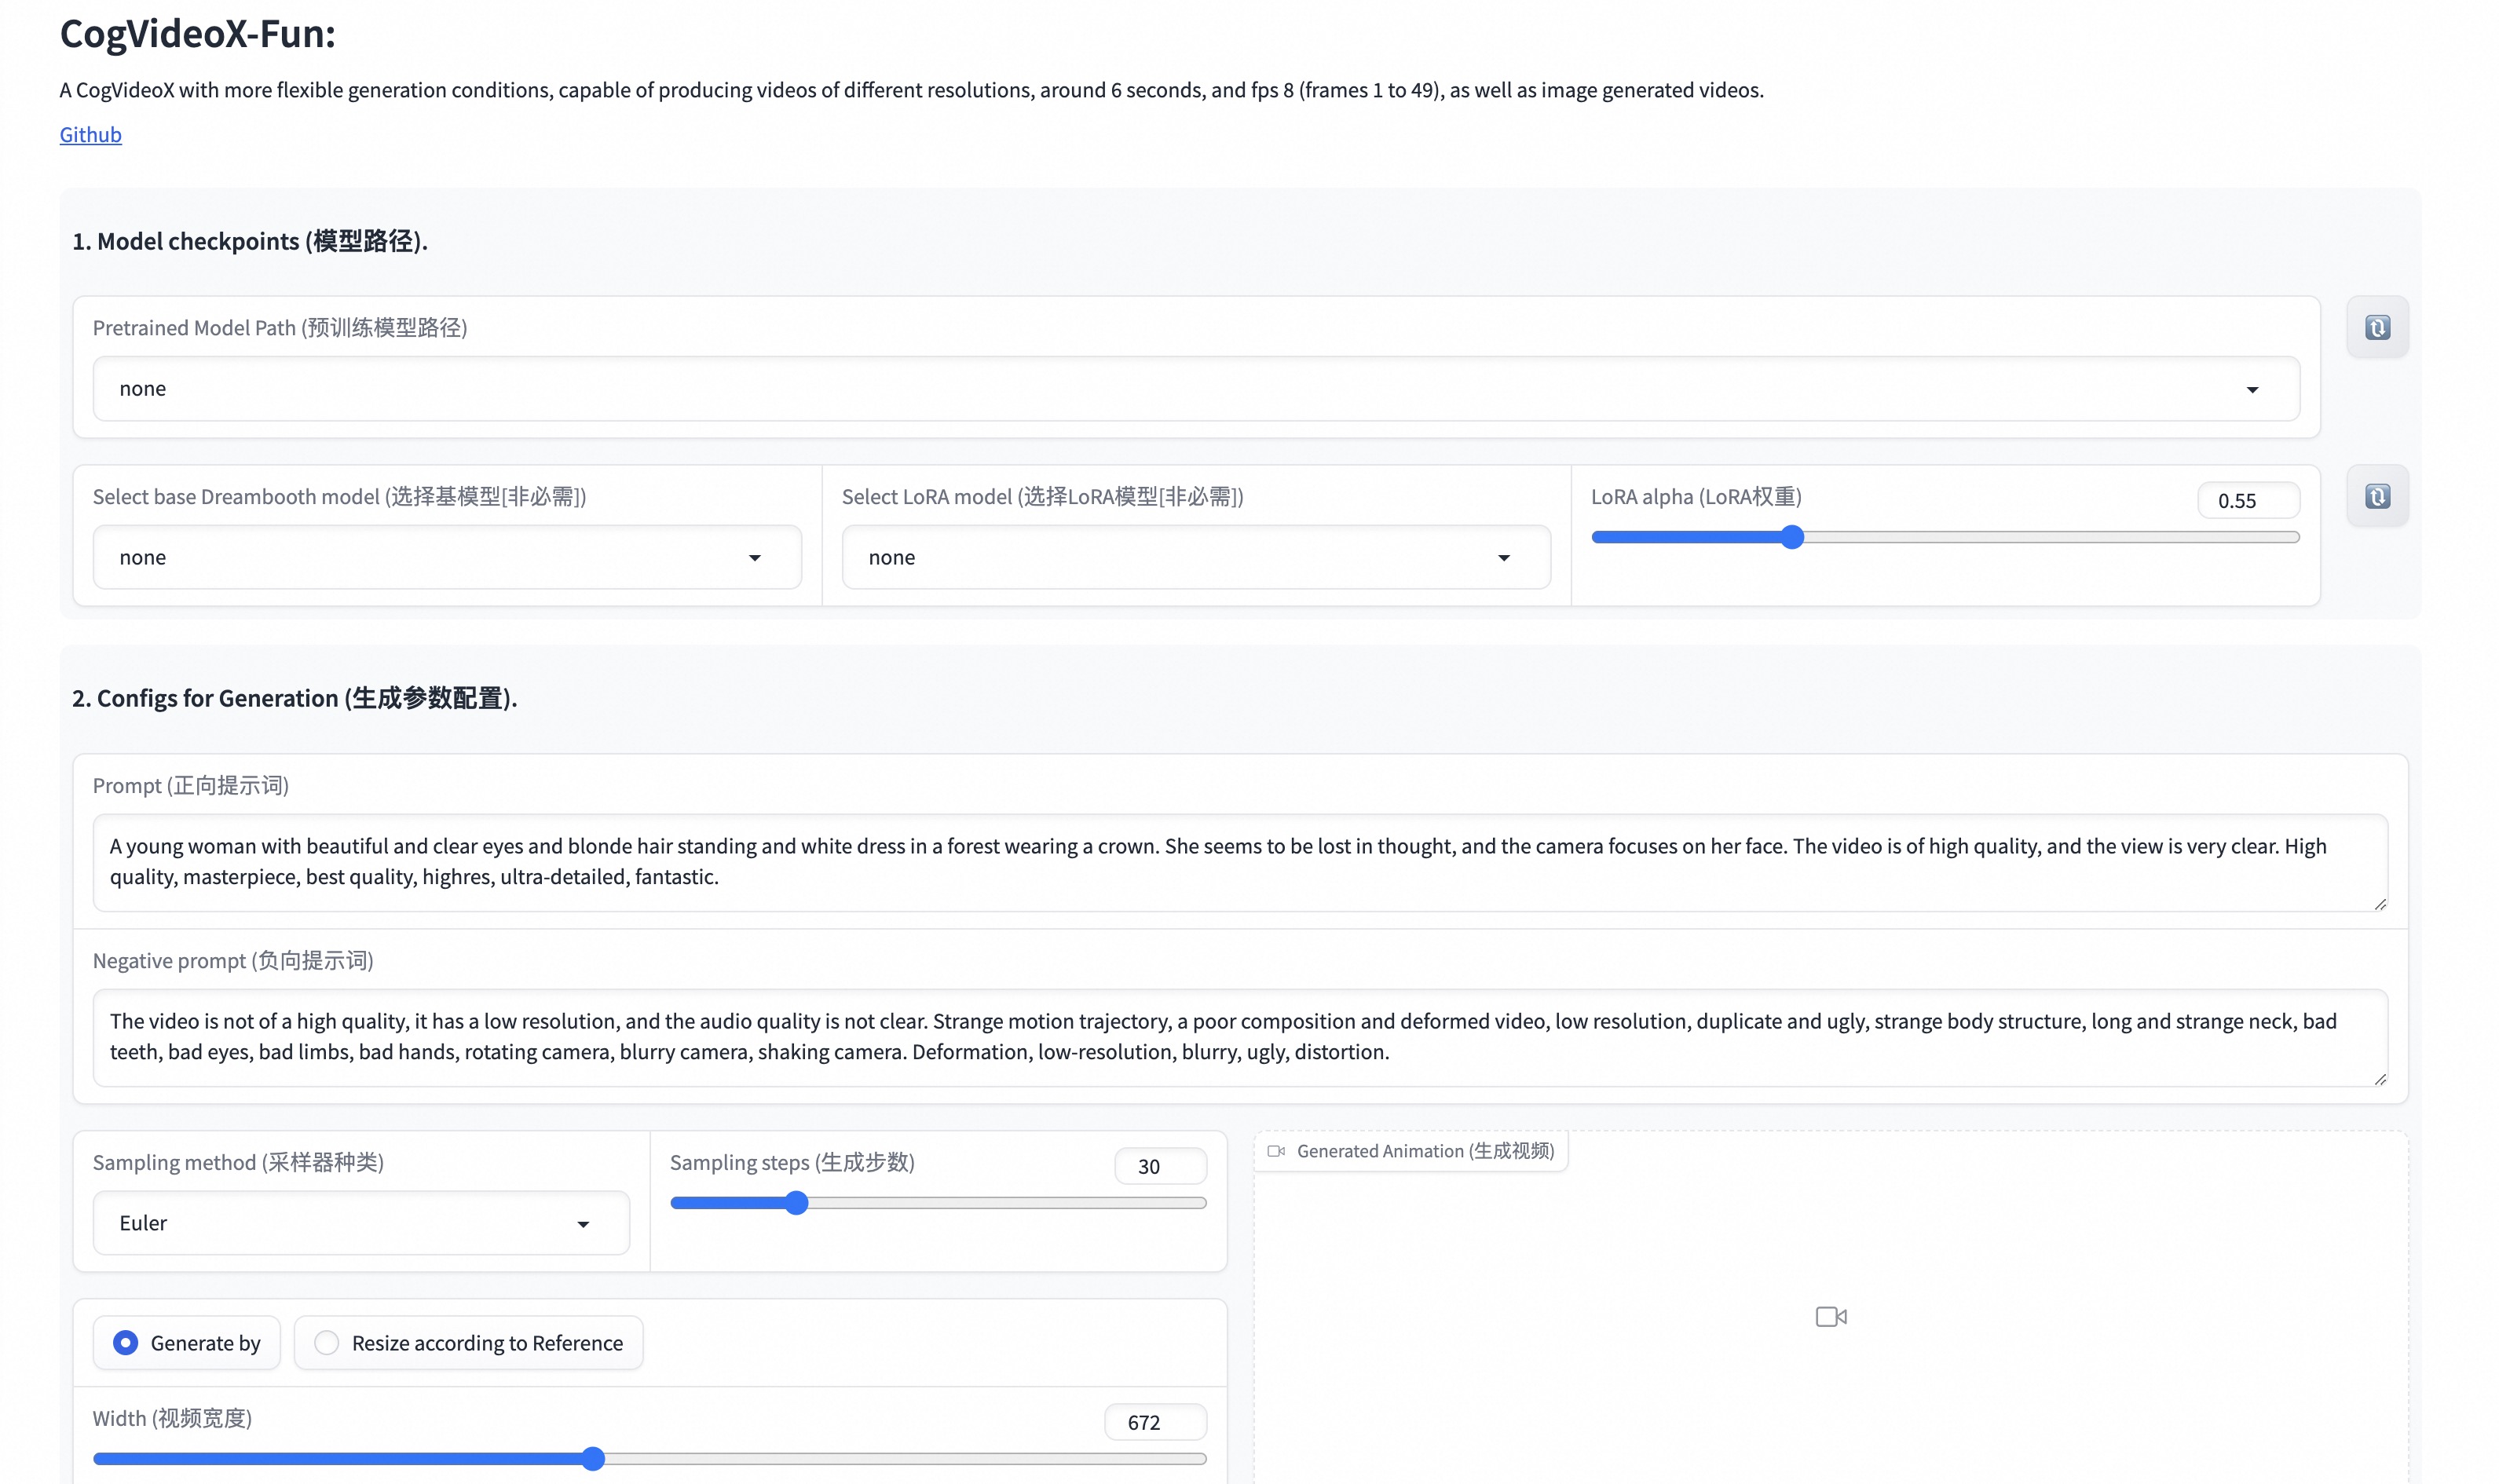
Our UI interface is as follows:
|
||||
|
||||
|
||||
# Quick Start
|
||||
### 1. Cloud usage: AliyunDSW/Docker
|
||||
#### a. From AliyunDSW
|
||||
# II. Quick Start and Usage
|
||||
|
||||
<a id="quick-start"></a>
|
||||
|
||||
## 1. Environment Preparation
|
||||
|
||||
### 1.1 Cloud Usage: AliyunDSW
|
||||
|
||||
DSW has free GPU time, which can be applied once by a user and is valid for 3 months after applying.
|
||||
|
||||
Aliyun provide free GPU time in [Freetier](https://free.aliyun.com/?product=9602825&crowd=enterprise&spm=5176.28055625.J_5831864660.1.e939154aRgha4e&scm=20140722.M_9974135.P_110.MO_1806-ID_9974135-MID_9974135-CID_30683-ST_8512-V_1), get it and use in Aliyun PAI-DSW to start CogVideoX-Fun within 5min!
|
||||
|
||||
[](https://gallery.pai-ml.com/#/preview/deepLearning/cv/cogvideox_fun)
|
||||
|
||||
#### b. From ComfyUI
|
||||
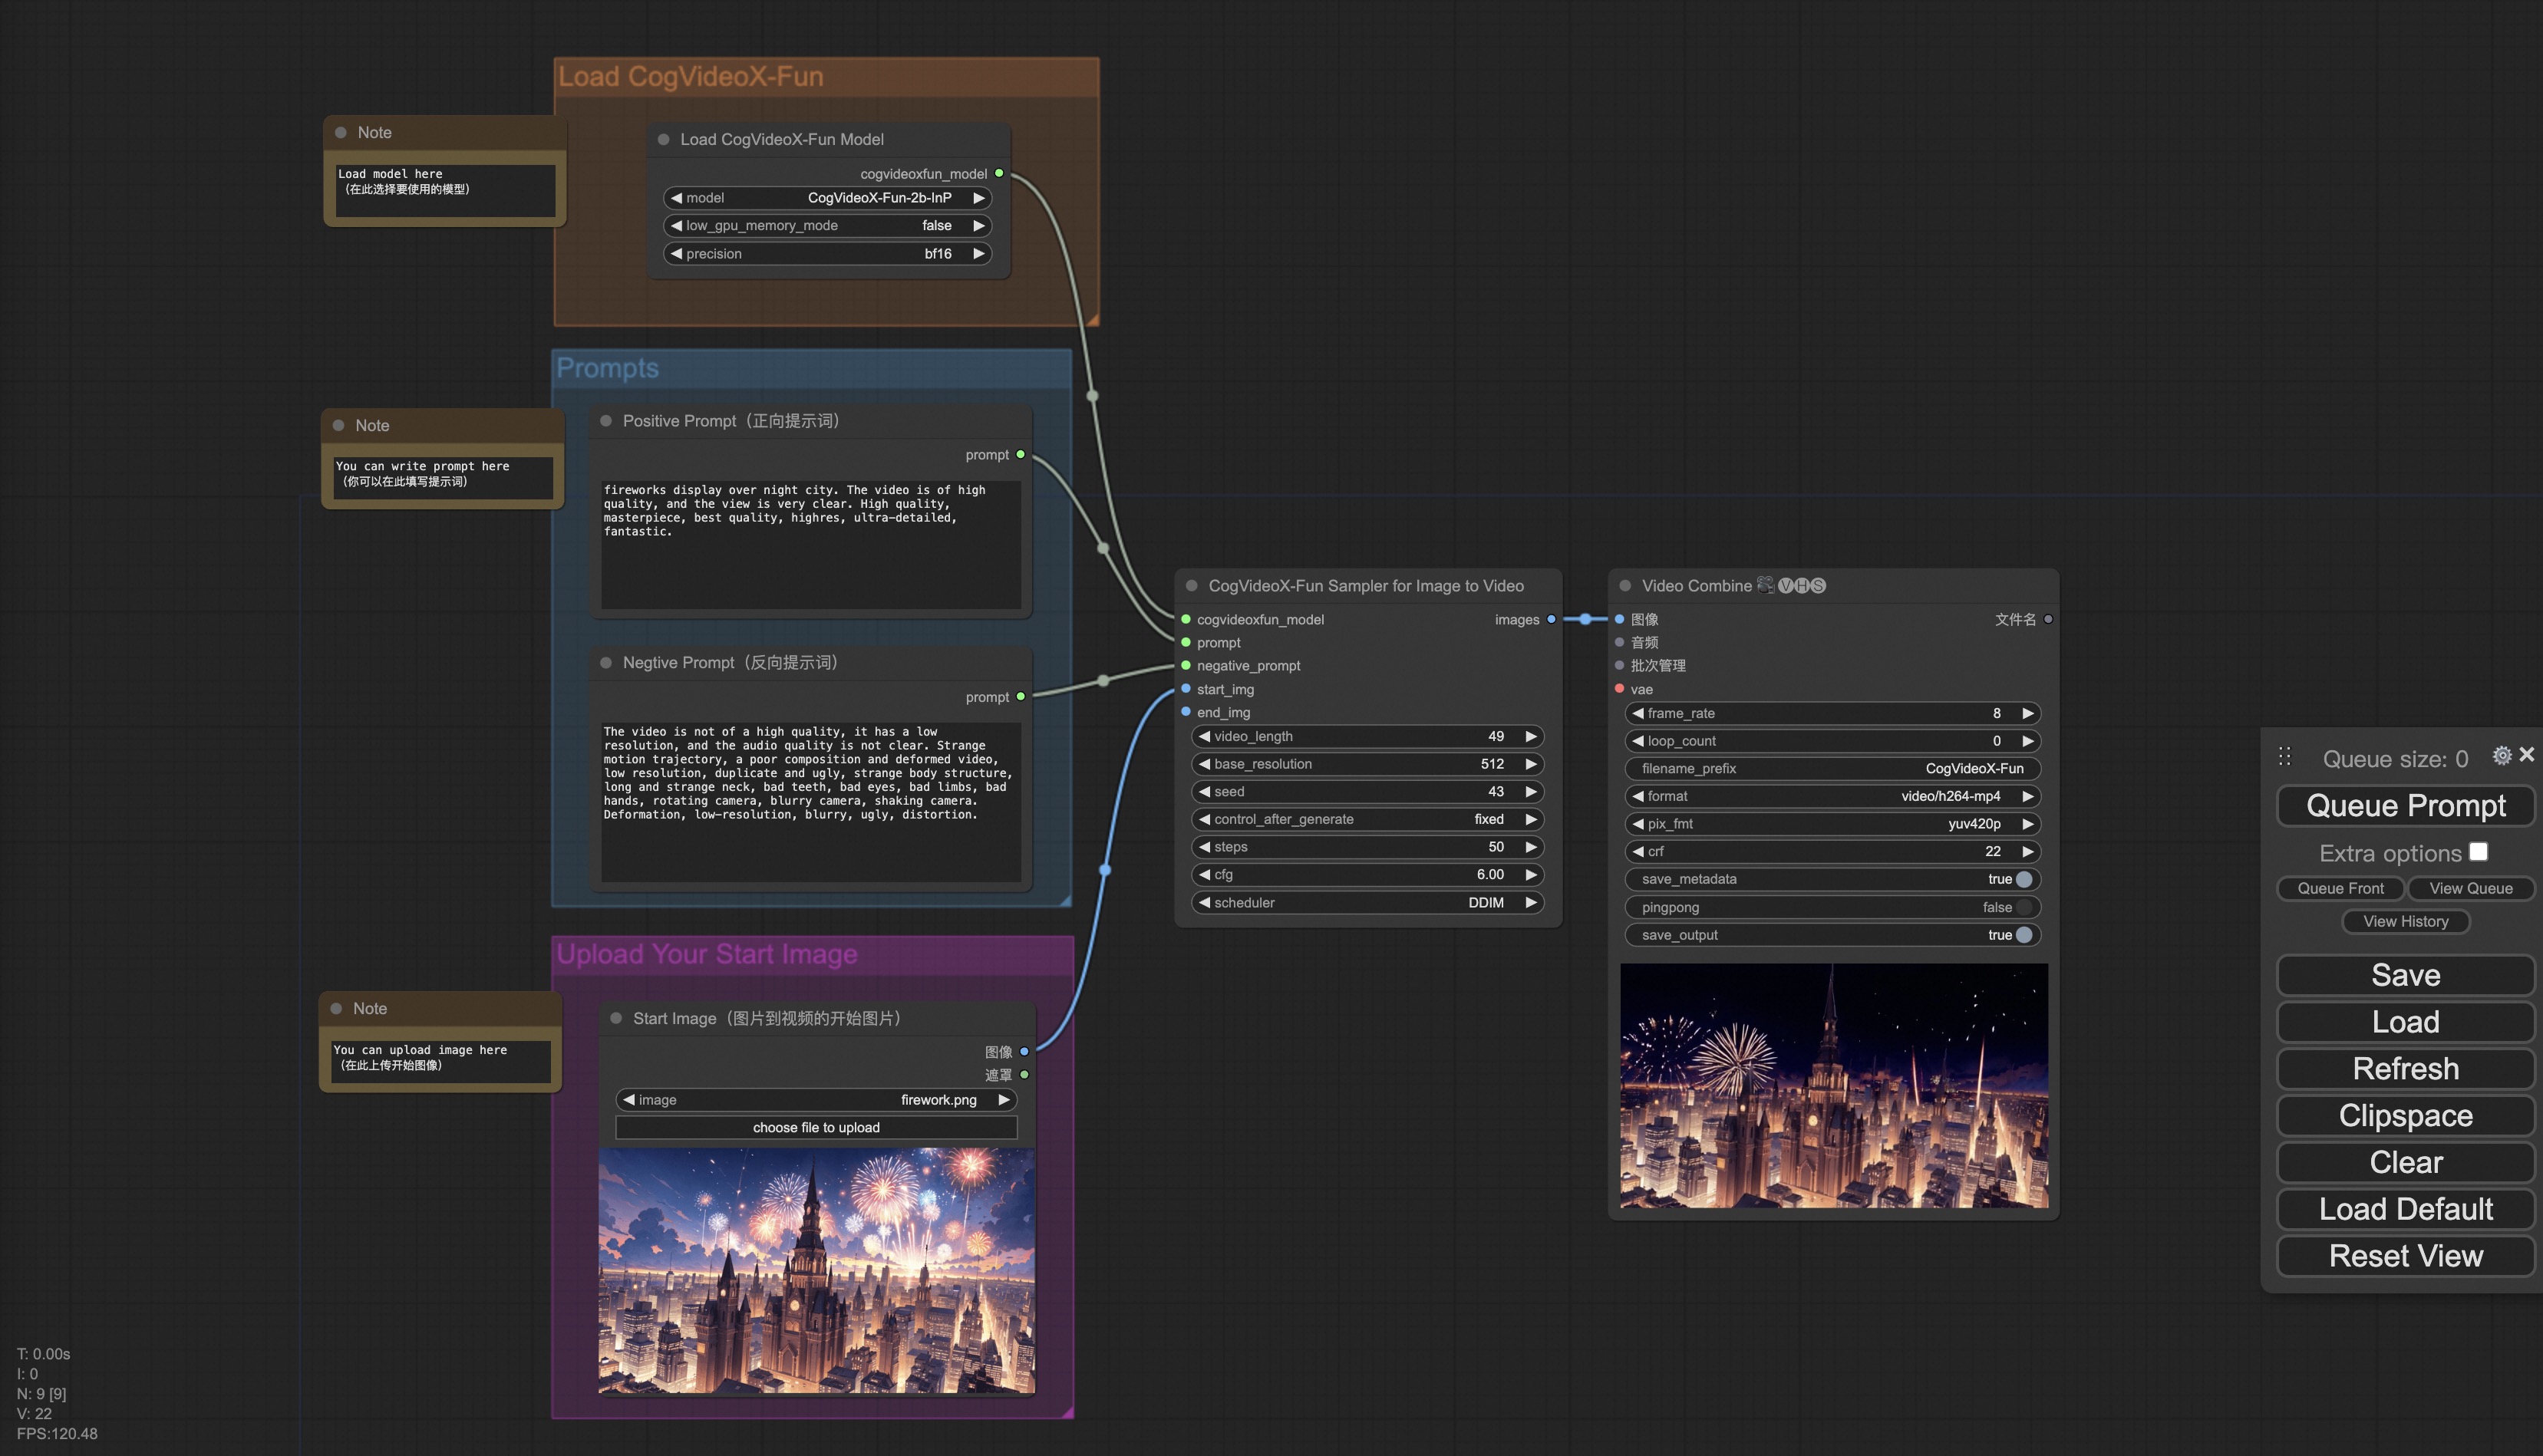
Our ComfyUI is as follows, please refer to [ComfyUI README](comfyui/README.md) for details.
|
||||
|
||||
### 1.2 Local Dependency Installation
|
||||
|
||||
We have verified this repo execution on the following environment:
|
||||
|
||||
The detailed of Windows:
|
||||
- OS: Windows 10
|
||||
- python: python3.10 & python3.11
|
||||
- pytorch: torch2.2.0
|
||||
- CUDA: 11.8 & 12.1
|
||||
- CUDNN: 8+
|
||||
- GPU: Nvidia-3060 12G & Nvidia-3090 24G
|
||||
|
||||
The detailed of Linux:
|
||||
- OS: Ubuntu 20.04, CentOS
|
||||
- python: python3.10 & python3.11
|
||||
- pytorch: torch2.2.0
|
||||
- CUDA: 11.8 & 12.1
|
||||
- CUDNN: 8+
|
||||
- GPU:Nvidia-V100 16G & Nvidia-A10 24G & Nvidia-A100 40G & Nvidia-A100 80G
|
||||
|
||||
We need about 60GB available on disk (for saving weights), please check!
|
||||
|
||||
### 1.3 Using Docker
|
||||
|
||||
#### c. From docker
|
||||
If you are using docker, please make sure that the graphics card driver and CUDA environment have been installed correctly in your machine.
|
||||
|
||||
Then execute the following commands in this way:
|
||||
@@ -89,30 +113,9 @@ mkdir models/Personalized_Model
|
||||
# https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP
|
||||
```
|
||||
|
||||
### 2. Local install: Environment Check/Downloading/Installation
|
||||
#### a. Environment Check
|
||||
We have verified this repo execution on the following environment:
|
||||
### 1.4 Weight Placement
|
||||
|
||||
The detailed of Windows:
|
||||
- OS: Windows 10
|
||||
- python: python3.10 & python3.11
|
||||
- pytorch: torch2.2.0
|
||||
- CUDA: 11.8 & 12.1
|
||||
- CUDNN: 8+
|
||||
- GPU: Nvidia-3060 12G & Nvidia-3090 24G
|
||||
|
||||
The detailed of Linux:
|
||||
- OS: Ubuntu 20.04, CentOS
|
||||
- python: python3.10 & python3.11
|
||||
- pytorch: torch2.2.0
|
||||
- CUDA: 11.8 & 12.1
|
||||
- CUDNN: 8+
|
||||
- GPU:Nvidia-V100 16G & Nvidia-A10 24G & Nvidia-A100 40G & Nvidia-A100 80G
|
||||
|
||||
We need about 60GB available on disk (for saving weights), please check!
|
||||
|
||||
#### b. Weights
|
||||
We'd better place the [weights](#model-zoo) along the specified path:
|
||||
We'd better place the [weights](#iii-supported-models) along the specified path:
|
||||
|
||||
**Via ComfyUI**:
|
||||
Put the models into the ComfyUI weights folder `ComfyUI/models/Fun_Models/`:
|
||||
@@ -138,7 +141,234 @@ Put the models into the ComfyUI weights folder `ComfyUI/models/Fun_Models/`:
|
||||
│ └── your trained trainformer model / your trained lora model (for UI load)
|
||||
```
|
||||
|
||||
# Video Result
|
||||
## 2. Inference Generation
|
||||
|
||||
<a id="video-gen"></a>
|
||||
|
||||
Video and image models share the exact same inference entry, provided by scripts or UI under `examples/{model_name}/`.
|
||||
|
||||
### 2.1 Entry Selection
|
||||
|
||||
| Entry | Suitable Scenario | Config Granularity |
|
||||
|--|--|--|
|
||||
| Python file | Batch generation, parameter debugging | Full parameters |
|
||||
| WebUI | Interactive experience | Common parameters only |
|
||||
| ComfyUI | Existing ComfyUI workflow | Node parameters |
|
||||
|
||||
Table: inference entry selection
|
||||
|
||||
### 2.2 GPU Memory Saving Options
|
||||
|
||||
Since Wan2.1 has a very large number of parameters, we need to consider memory optimization strategies to adapt to consumer-grade GPUs. We provide `GPU_memory_mode` for each prediction file, allowing you to choose between `model_cpu_offload`, `model_cpu_offload_and_qfloat8`, and `sequential_cpu_offload`. This solution is also applicable to CogVideoX-Fun generation.
|
||||
|
||||
- `model_cpu_offload`: The entire model is moved to the CPU after use, saving some GPU memory.
|
||||
- `model_cpu_offload_and_qfloat8`: The entire model is moved to the CPU after use, and the transformer model is quantized to float8, saving more GPU memory.
|
||||
- `sequential_cpu_offload`: Each layer of the model is moved to the CPU after use. It is slower but saves a significant amount of GPU memory.
|
||||
|
||||
`qfloat8` may slightly reduce model performance but saves more GPU memory. If you have sufficient GPU memory, it is recommended to use `model_cpu_offload`.
|
||||
|
||||
### 2.3 Via Python Files
|
||||
|
||||
##### i. Single-GPU Inference:
|
||||
|
||||
- **Step 1**: Download the corresponding [weights](#iii-supported-models) and place them in the `models` folder.
|
||||
- **Step 2**: Use different files for prediction based on the weights and prediction goals. This library currently supports CogVideoX-Fun, Wan2.1, and Wan2.1-Fun. Different models are distinguished by folder names under the `examples` folder, and their supported features vary. Use them accordingly. Below is an example using CogVideoX-Fun:
|
||||
- **Text-to-Video**:
|
||||
- Modify `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_t2v.py`.
|
||||
- Run the file `examples/cogvideox_fun/predict_t2v.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos`.
|
||||
- **Image-to-Video**:
|
||||
- Modify `validation_image_start`, `validation_image_end`, `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_i2v.py`.
|
||||
- `validation_image_start` is the starting image of the video, and `validation_image_end` is the ending image of the video.
|
||||
- Run the file `examples/cogvideox_fun/predict_i2v.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos_i2v`.
|
||||
- **Video-to-Video**:
|
||||
- Modify `validation_video`, `validation_image_end`, `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_v2v.py`.
|
||||
- `validation_video` is the reference video for video-to-video generation. You can use the following demo video: [Demo Video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/play_guitar.mp4).
|
||||
- Run the file `examples/cogvideox_fun/predict_v2v.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos_v2v`.
|
||||
- **Controlled Video Generation (Canny, Pose, Depth, etc.)**:
|
||||
- Modify `control_video`, `validation_image_end`, `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_v2v_control.py`.
|
||||
- `control_video` is the control video extracted using operators such as Canny, Pose, or Depth. You can use the following demo video: [Demo Video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/pose.mp4).
|
||||
- Run the file `examples/cogvideox_fun/predict_v2v_control.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos_v2v_control`.
|
||||
- **Step 3**: If you want to integrate other backbones or Loras trained by yourself, modify `lora_path` and relevant paths in `examples/{model_name}/predict_t2v.py` or `examples/{model_name}/predict_i2v.py` as needed.
|
||||
|
||||
##### ii. Multi-GPU Inference:
|
||||
When using multi-GPU inference, please make sure to install the xfuser. We recommend installing xfuser==0.4.2 and yunchang==0.6.2.
|
||||
```
|
||||
pip install xfuser==0.4.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
pip install yunchang==0.6.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
```
|
||||
|
||||
Please ensure that the product of `ulysses_degree` and `ring_degree` equals the number of GPUs being used. For example, if you are using 8 GPUs, you can set `ulysses_degree=2` and `ring_degree=4`, or alternatively `ulysses_degree=4` and `ring_degree=2`.
|
||||
|
||||
- `ulysses_degree` performs parallelization after splitting across the heads.
|
||||
- `ring_degree` performs parallelization after splitting across the sequence.
|
||||
|
||||
Compared to `ulysses_degree`, `ring_degree` incurs higher communication costs. Therefore, when setting these parameters, you should take into account both the sequence length and the number of heads in the model.
|
||||
|
||||
Let’s take 8-GPU parallel inference as an example:
|
||||
|
||||
- **For Wan2.1-Fun-V1.1-14B-InP**, which has 40 heads, `ulysses_degree` should be set to a divisor of 40 (e.g., 2, 4, 8, etc.). Thus, when using 8 GPUs for parallel inference, you can set `ulysses_degree=8` and `ring_degree=1`.
|
||||
|
||||
- **For Wan2.1-Fun-V1.1-1.3B-InP**, which has 12 heads, `ulysses_degree` should be set to a divisor of 12 (e.g., 2, 4, etc.). Thus, when using 8 GPUs for parallel inference, you can set `ulysses_degree=4` and `ring_degree=2`.
|
||||
|
||||
After setting the parameters, run the following command for parallel inference:
|
||||
|
||||
```sh
|
||||
torchrun --nproc-per-node=8 examples/wan2.1_fun/predict_t2v.py
|
||||
```
|
||||
|
||||
### 2.4 Via the Web UI
|
||||
|
||||
The web UI supports text-to-video, image-to-video, video-to-video, and controlled video generation (Canny, Pose, Depth, etc.). This library currently supports CogVideoX-Fun, Wan2.1, and Wan2.1-Fun. Different models are distinguished by folder names under the `examples` folder, and their supported features vary. Use them accordingly. Below is an example using CogVideoX-Fun:
|
||||
|
||||
- **Step 1**: Download the corresponding [weights](#iii-supported-models) and place them in the `models` folder.
|
||||
- **Step 2**: Run the file `examples/cogvideox_fun/app.py` to access the Gradio interface.
|
||||
- **Step 3**: Select the generation model on the page, fill in `prompt`, `neg_prompt`, `guidance_scale`, and `seed`, click "Generate," and wait for the results. The generated videos will be saved in the `sample` folder.
|
||||
|
||||
### 2.5 Via ComfyUI
|
||||
|
||||
For details, refer to [ComfyUI README](comfyui/README.md).
|
||||
|
||||
|
||||
## 3. Model Training
|
||||
|
||||
A complete model training pipeline consists of data preprocessing and Video DiT training.
|
||||
|
||||
### 3.1 Data Preprocessing
|
||||
|
||||
<a id="data-preprocess"></a>
|
||||
Training documents for each model are unified under `scripts/{model_name}/`. For details, see [3.3 Training Documents per Model](#33-training-documents-per-model).
|
||||
|
||||
A complete data preprocessing link for long video segmentation, cleaning, and description can refer to [README](videox_fun/video_caption/README.md) in the video captions section.
|
||||
|
||||
If you want to train a text to image and video generation model. You need to arrange the dataset in this format.
|
||||
|
||||
```
|
||||
📦 project/
|
||||
├── 📂 datasets/
|
||||
│ ├── 📂 internal_datasets/
|
||||
│ ├── 📂 train/
|
||||
│ │ ├── 📄 00000001.mp4
|
||||
│ │ ├── 📄 00000002.jpg
|
||||
│ │ └── 📄 .....
|
||||
│ └── 📄 json_of_internal_datasets.json
|
||||
```
|
||||
|
||||
The json_of_internal_datasets.json is a standard JSON file. The file_path in the json can to be set as relative path, as shown in below:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "train/00000001.mp4",
|
||||
"text": "A group of young men in suits and sunglasses are walking down a city street.",
|
||||
"type": "video"
|
||||
},
|
||||
{
|
||||
"file_path": "train/00000002.jpg",
|
||||
"text": "A group of young men in suits and sunglasses are walking down a city street.",
|
||||
"type": "image"
|
||||
},
|
||||
.....
|
||||
]
|
||||
```
|
||||
|
||||
You can also set the path as absolute path as follow:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "/mnt/data/videos/00000001.mp4",
|
||||
"text": "A group of young men in suits and sunglasses are walking down a city street.",
|
||||
"type": "video"
|
||||
},
|
||||
{
|
||||
"file_path": "/mnt/data/train/00000001.jpg",
|
||||
"text": "A group of young men in suits and sunglasses are walking down a city street.",
|
||||
"type": "image"
|
||||
},
|
||||
.....
|
||||
]
|
||||
```
|
||||
|
||||
### 3.2 Video DiT Training
|
||||
|
||||
<a id="dit-train"></a>
|
||||
The training scripts and launch sh files for each model are located under `scripts/{model_name}/`. The sh file names vary by task, such as `train.sh`, `train_lora.sh`, `train_control.sh`, `train_control_distill.sh`, etc.; refer to the actual files in the directory.
|
||||
|
||||
If the data format is relative path during data preprocessing, please set ```scripts/{model_name}/train.sh``` as follow.
|
||||
```
|
||||
export DATASET_NAME="datasets/internal_datasets/"
|
||||
export DATASET_META_NAME="datasets/internal_datasets/json_of_internal_datasets.json"
|
||||
```
|
||||
|
||||
If the data format is absolute path during data preprocessing, please set ```scripts/{model_name}/train.sh``` as follow (`DATASET_NAME` is left empty so the dataset directory prefix is no longer concatenated).
|
||||
```
|
||||
export DATASET_NAME=""
|
||||
export DATASET_META_NAME="/mnt/data/json_of_internal_datasets.json"
|
||||
```
|
||||
|
||||
Finally, run the corresponding script.
|
||||
```sh
|
||||
sh scripts/{model_name}/train.sh
|
||||
```
|
||||
|
||||
### 3.3 Training Documents per Model
|
||||
|
||||
For parameter details, training documents for each model are unified under `scripts/{model_name}/`.
|
||||
|
||||
| Model | Baseline Training | LoRA Training | Others |
|
||||
|--|--|--|--|
|
||||
| Wan2.1-Fun | [EN](scripts/wan2.1_fun/README_TRAIN.md) / [ZH](scripts/wan2.1_fun/README_TRAIN_zh-CN.md) | [EN](scripts/wan2.1_fun/README_TRAIN_LORA.md) / [ZH](scripts/wan2.1_fun/README_TRAIN_LORA_zh-CN.md) | [Control EN](scripts/wan2.1_fun/README_TRAIN_CONTROL.md)、[Reward LoRA](scripts/wan2.1_fun/README_TRAIN_REWARD.md) |
|
||||
| Wan2.2 | [EN](scripts/wan2.2/README_TRAIN.md) / [ZH](scripts/wan2.2/README_TRAIN_zh-CN.md) | [EN](scripts/wan2.2/README_TRAIN_LORA.md) / [ZH](scripts/wan2.2/README_TRAIN_LORA_zh-CN.md) | [Distill EN](scripts/wan2.2/README_TRAIN_DISTILL.md)、[S2V](scripts/wan2.2/README_TRAIN_S2V.md)、[Animate](scripts/wan2.2/README_TRAIN_ANIMATE.md) |
|
||||
| Wan2.2-Fun | [EN](scripts/wan2.2_fun/README_TRAIN.md) / [ZH](scripts/wan2.2_fun/README_TRAIN_zh-CN.md) | [EN](scripts/wan2.2_fun/README_TRAIN_LORA.md) / [ZH](scripts/wan2.2_fun/README_TRAIN_LORA_zh-CN.md) | [Control LoRA EN](scripts/wan2.2_fun/README_TRAIN_CONTROL_LORA.md) |
|
||||
| CogVideoX-Fun | [EN](scripts/cogvideox_fun/README_TRAIN.md) / [ZH](scripts/cogvideox_fun/README_TRAIN_zh-CN.md) | [EN](scripts/cogvideox_fun/README_TRAIN_LORA.md) / [ZH](scripts/cogvideox_fun/README_TRAIN_LORA_zh-CN.md) | [Control EN](scripts/cogvideox_fun/README_TRAIN_CONTROL.md)、[Reward LoRA](scripts/cogvideox_fun/README_TRAIN_REWARD.md) |
|
||||
| Qwen-Image | [EN](scripts/qwenimage/README_TRAIN.md) / [ZH](scripts/qwenimage/README_TRAIN_zh-CN.md) | [EN](scripts/qwenimage/README_TRAIN_LORA.md) / [ZH](scripts/qwenimage/README_TRAIN_LORA_zh-CN.md) | [Edit EN](scripts/qwenimage/README_TRAIN_EDIT.md) |
|
||||
| Qwen-Image-2.1 | [EN](scripts/qwenimage21/README_TRAIN.md) / [ZH](scripts/qwenimage21/README_TRAIN_zh-CN.md) | - | - |
|
||||
| Z-Image | [EN](scripts/z_image/README_TRAIN.md) / [ZH](scripts/z_image/README_TRAIN_zh-CN.md) | [EN](scripts/z_image/README_TRAIN_LORA.md) / [ZH](scripts/z_image/README_TRAIN_LORA_zh-CN.md) | [GRPO LoRA EN](scripts/z_image/README_TRAIN_GRPO_LORA.md) |
|
||||
|
||||
For other models, check the READMEs under `scripts/{model_name}/`.
|
||||
|
||||
# III. Supported Models
|
||||
|
||||
The table below summarizes currently supported model families and weights. Video and image models share the same inference and training entry. Each row represents one model family; the fourth column is an embedded four-column HTML table (Weight, Hugging Face, ModelScope, Description). 🤗 is Hugging Face, 🤖 is ModelScope (recommended for users in mainland China), and `-` means the corresponding channel has no public repo or requires authentication. For training docs of each model, see [3.3 Training Documents per Model](#33-training-documents-per-model).
|
||||
|
||||
| Model Family | Modality | Supported Tasks | Weight / Download / Description |
|
||||
|--|--|--|--|
|
||||
| Wan2.2-Fun | Video | Series trained by this project on Wan2.2, covering T2V, I2V, first/last frame, controlled generation, and camera control | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-A14B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-Fun-14B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-A14B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-Fun-14B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-A14B-Control-Camera</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control-Camera">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control-Camera">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-Fun-14B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-5B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-Fun-5B text-to-video weights trained at 121 frames, 24 FPS, supporting first/last frame prediction.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-5B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-Fun-5B video control weights, supporting control conditions like Canny, Depth, Pose, MLSD, and trajectory control. Trained at 121 frames, 24 FPS, with multilingual prediction support.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-5B-Control-Camera</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control-Camera">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control-Camera">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-Fun-5B camera lens control weights. Trained at 121 frames, 24 FPS, with multilingual prediction support.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-Reward-LoRAs</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-Reward-LoRAs">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-Reward-LoRAs">🤖</a></td><td valign="top" style="padding:2px 0;">Reward LoRAs that optimize Wan2.2-Fun generated videos via reward backpropagation</td></tr></table> |
|
||||
| Wan2.2-VACE-Fun | Video | Series trained by this project with the VACE scheme, covering controlled generation and subject reference | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-VACE-Fun-A14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-VACE-Fun-A14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-VACE-Fun-A14B">🤖</a></td><td valign="top" style="padding:2px 0;">Control weights for Wan2.2 trained using the VACE scheme (based on the base model Wan2.2-T2V-A14B), supporting various control conditions such as Canny, Depth, Pose, MLSD, trajectory control, etc. It supports video generation by specifying the subject. It supports multi-resolution (512, 768, 1024) video prediction, and is trained with 81 frames at 16 FPS. It also supports multi-language prediction.</td></tr></table> |
|
||||
| Wan2.2 | Video | Official Wan weights covering T2V, I2V, audio-driven, and character animation; can be used as training baseline for Wan2.2-Fun | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-TI2V-5B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.2-TI2V-5B">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-5B text/image-to-video weights</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-T2V-A14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-T2V-A14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.2-T2V-A14B">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-14B text-to-video weights</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-I2V-A14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-I2V-A14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.2-I2V-A14B">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-14B image-to-video weights</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-S2V-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-S2V-14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Wan-AI/Wan2.2-S2V-14B">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-14B audio-to-video weights, speaker-driven digital human</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Animate-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-Animate-14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Wan-AI/Wan2.2-Animate-14B">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-14B character replacement and motion transfer weights; repo contains multiple precision files</td></tr></table> |
|
||||
| Wan2.1-Fun V1.1 | Video | V1.1 series trained by this project on Wan2.1, multi-resolution (512/768/1024), 81 frames at 16fps, covering T2V, I2V, first/last frame, controlled generation, and camera control | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-1.3B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-V1.1-1.3B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-14B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-V1.1-14B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-1.3B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-V1.1-1.3B video control weights support various control conditions such as Canny, Depth, Pose, MLSD, etc., supports reference image + control condition-based control, and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-14B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-V1.1-14B video control weights support various control conditions such as Canny, Depth, Pose, MLSD, etc., supports reference image + control condition-based control, and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-1.3B-Control-Camera</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control-Camera">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control-Camera">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-V1.1-1.3B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-14B-Control-Camera</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control-Camera">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control-Camera">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-V1.1-14B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction.</td></tr></table> |
|
||||
| Wan2.1-Fun V1.0 | Video | V1.0 series trained by this project on Wan2.1; same capabilities as V1.1 but without camera control | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-1.3B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-1.3B text-to-video weights, trained at multiple resolutions, supporting start and end frame prediction.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-14B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-14B text-to-video weights, trained at multiple resolutions, supporting start and end frame prediction.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-1.3B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-1.3B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-14B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-14B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-Reward-LoRAs</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-Reward-LoRAs">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-Reward-LoRAs">🤖</a></td><td valign="top" style="padding:2px 0;">Alignment LoRAs trained with reward backpropagation</td></tr></table> |
|
||||
| Wan2.1 | Video | Official Wan weights covering T2V, I2V, audio-driven, and controlled generation; can be used as training baseline for Wan2.1-Fun | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-T2V-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-1.3B">🤖</a></td><td valign="top" style="padding:2px 0;">1.3B文生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-T2V-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-T2V-14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-14B">🤖</a></td><td valign="top" style="padding:2px 0;">14B文生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-I2V-14B-480P</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-480P">🤖</a></td><td valign="top" style="padding:2px 0;">480P图生视频,是InfiniteTalk的基础模型</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-I2V-14B-720P</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P">🤖</a></td><td valign="top" style="padding:2px 0;">Wan 2.1-14B-720P image-to-video model weights</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-VACE-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-VACE-1.3B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Wan-AI/Wan2.1-VACE-1.3B">🤖</a></td><td valign="top" style="padding:2px 0;">1.3B VACE control and subject reference</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-VACE-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-VACE-14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Wan-AI/Wan2.1-VACE-14B">🤖</a></td><td valign="top" style="padding:2px 0;">14B VACE control and subject reference</td></tr></table> |
|
||||
| Self-Forcing / Causal-Forcing / Flex-Forcing | Video | Autoregressive distillation schemes covering streaming, interactive generation, and flexible chunked attention | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Self-Forcing</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/gdhe17/Self-Forcing">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/AI-ModelScope/Self-Forcing">🤖</a></td><td valign="top" style="padding:2px 0;">Autoregressive distillation weights, use with Wan2.1-T2V for streaming and interactive generation; Flex-Forcing (chunk-wise causal/bidirectional attention) weights are produced by `scripts/wan2.1_flex_forcing`</td></tr></table> |
|
||||
| TurboWan / TurboDiffusion | Video | Distilled few-step weights publicly released by the TurboDiffusion scheme | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">TurboWan2.1-T2V-1.3B-480P</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/TurboDiffusion/TurboWan2.1-T2V-1.3B-480P">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/TurboDiffusion/TurboWan2.1-T2V-1.3B-480P">🤖</a></td><td valign="top" style="padding:2px 0;">1.3B text-to-video distilled weights; officially released as .pth, the repo also ships a quantised version</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">TurboWan2.2-I2V-A14B-720P</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/TurboDiffusion/TurboWan2.2-I2V-A14B-720P">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/TurboDiffusion/TurboWan2.2-I2V-A14B-720P">🤖</a></td><td valign="top" style="padding:2px 0;">14B image-to-video distilled weights; the repo contains low/high noise variants (plus quantised). Place them in Personalized_Model and reference via transformer_path / transformer_high_path</td></tr></table> |
|
||||
| CogVideoX-Fun V1.5 | Video | Official CogVideoX-Fun V1.5 weights, multi-resolution (512/768/1024), 85 frames at 8fps, covering I2V and reward alignment | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.5-5b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-5b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-5b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024) and has been trained on 85 frames at a rate of 8 frames per second.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.5-Reward-LoRAs</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-Reward-LoRAs">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs">🤖</a></td><td valign="top" style="padding:2px 0;">奖励反向传播训练的对齐LoRA</td></tr></table> |
|
||||
| CogVideoX-Fun V1.1 | Video | Official CogVideoX-Fun V1.1 weights, multi-resolution (512/768/1024/1280), 49 frames at 8fps, covering I2V, pose control, controlled generation, and reward alignment | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-2b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-5b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Noise has been added to the reference image, and the amplitude of motion is greater compared to V1.0.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-2b-Pose</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Pose">🤖</a></td><td valign="top" style="padding:2px 0;">Our official pose-control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-5b-Pose</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Pose">🤖</a></td><td valign="top" style="padding:2px 0;">Our official pose-control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-2b-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Control">🤖</a></td><td valign="top" style="padding:2px 0;">Our official control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Supporting various control conditions such as Canny, Depth, Pose, MLSD, etc.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-5b-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Control">🤖</a></td><td valign="top" style="padding:2px 0;">Our official control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Supporting various control conditions such as Canny, Depth, Pose, MLSD, etc.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-Reward-LoRAs</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-Reward-LoRAs">🤖</a></td><td valign="top" style="padding:2px 0;">奖励反向传播训练的对齐LoRA</td></tr></table> |
|
||||
| CogVideoX-Fun V1.0 | Video | Legacy weights trained at 49 frames 8fps, superseded by V1.1/V1.5 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-2b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-2b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-5b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-5b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second.</td></tr></table> |
|
||||
| HunyuanVideo | Video | Official diffusers-format weights; this project directly supports inference and LoRA training | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">HunyuanVideo</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/hunyuanvideo-community/HunyuanVideo">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Tencent-Hunyuan/HunyuanVideo">🤖</a></td><td valign="top" style="padding:2px 0;">文生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">HunyuanVideo-I2V</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/hunyuanvideo-community/HunyuanVideo-I2V">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Tencent-Hunyuan/HunyuanVideo-I2V">🤖</a></td><td valign="top" style="padding:2px 0;">图生视频</td></tr></table> |
|
||||
| MiniMax-H3 | Video | Official video generation weights and the ControlNet trained by this project | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">MiniMax-H3</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/MiniMaxAI/MiniMax-H3">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/MiniMax/MiniMax-H3">🤖</a></td><td valign="top" style="padding:2px 0;">Official MiniMax-H3 T2V/I2V weights</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">MiniMax-H3-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/MiniMax-H3-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/MiniMax-H3-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet trained by this project, supports multiple control conditions and trajectory control</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">MiniMax-H3-Fun-Controlnet-Union-2.0</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/MiniMax-H3-Fun-Controlnet-Union-2.0">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/MiniMax-H3-Fun-Controlnet-Union-2.0">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet trained by this project (2.0), supporting multiple control conditions, trajectory control, and inpaint checkpoints</td></tr></table> |
|
||||
| TaoMate-H3 | Video+Audio | Official streaming audio-video generation adapter built on MiniMax-H3 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">TaoMate-H3-Adapter</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/TaoLiveAIGC/TaoMate-H3">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/TaoLiveAIGC/TaoMate-H3">🤖</a></td><td valign="top" style="padding:2px 0;">Official rank-128 adapter (step-3000 EMA) with a built-in 3-step distilled schedule for streaming speech-driven generation; requires the MiniMax-H3 base weights</td></tr></table> |
|
||||
| LTX-2 | Video+Audio | Official DiT audio-video joint generation weights | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">LTX-2</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Lightricks/LTX-2">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Lightricks/LTX-2">🤖</a></td><td valign="top" style="padding:2px 0;">Official audio-video joint generation weights; repo contains multiple precision files</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">LTX-2.3-Diffusers</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/dg845/LTX-2.3-Diffusers">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">v2.3 requires community-converted diffusers weights; see Lightricks/LTX-2.3 for official weights</td></tr></table> |
|
||||
| LongCat-Video | Video | Official long-video generation weights; supports LoRA training | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">LongCat-Video</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/meituan-longcat/LongCat-Video">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/meituan-longcat/LongCat-Video">🤖</a></td><td valign="top" style="padding:2px 0;">Official LongCat-Video T2V weights</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">LongCat-Video-Avatar</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/meituan-longcat/LongCat-Video-Avatar">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/meituan-longcat/LongCat-Video-Avatar">🤖</a></td><td valign="top" style="padding:2px 0;">Official LongCat-Video avatar/digital-human weights</td></tr></table> |
|
||||
| FantasyTalking | Audio-driven Video | Audio-conditioned incremental weights; requires base video weights and audio encoder | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">FantasyTalking</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/acvlab/FantasyTalking">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/amap_cvlab/FantasyTalking">🤖</a></td><td valign="top" style="padding:2px 0;">需搭配Wan2.1-I2V-14B-720P使用</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">wav2vec2-base-960h</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/facebook/wav2vec2-base-960h">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/AI-ModelScope/wav2vec2-base-960h">🤖</a></td><td valign="top" style="padding:2px 0;">音频编码器,放入基础权重目录并命名为audio_encoder</td></tr></table> |
|
||||
| InfiniteTalk | Audio-driven Video | Audio-conditioned incremental weights; requires base video weights and audio encoder | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">InfiniteTalk</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/MeiGen-AI/InfiniteTalk">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/MeiGen-AI/InfiniteTalk">🤖</a></td><td valign="top" style="padding:2px 0;">Official InfiniteTalk audio-driven weights</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">chinese-wav2vec2-base</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/TencentGameMate/chinese-wav2vec2-base">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/TencentGameMate/chinese-wav2vec2-base">🤖</a></td><td valign="top" style="padding:2px 0;">Chinese audio encoder</td></tr></table> |
|
||||
| FlashHead | Audio-driven Video | Official high-fidelity audio-driven head weights | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">SoulX-FlashHead-1_3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Soul-AILab/SoulX-FlashHead-1_3B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Soul-AILab/SoulX-FlashHead-1_3B">🤖</a></td><td valign="top" style="padding:2px 0;">SoulX FlashHead 1.3B audio-driven head weights; requires wav2vec audio encoder</td></tr></table> |
|
||||
| MOVA | Video+Audio | Official MOVA weights | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">MOVA-360p</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/OpenMOSS-Team/MOVA-360p">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/OpenMOSS/MOVA-360p">🤖</a></td><td valign="top" style="padding:2px 0;">Image-to-video and audio-video joint generation</td></tr></table> |
|
||||
| LingBot | Video | Camera-controllable world model; directory structure matches Wan2.2-I2V-A14B | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-world-base-cam</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-world-base-cam">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-world-base-cam">🤖</a></td><td valign="top" style="padding:2px 0;">Camera-control baseline weights</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-video-rewriter-lora</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-video-rewriter-lora">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-video-rewriter-lora">🤖</a></td><td valign="top" style="padding:2px 0;">rewriter LoRA; use with Qwen3.6-27B generated structured captions</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-video-dense-1.3b</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-video-dense-1.3b">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-video-dense-1.3b">🤖</a></td><td valign="top" style="padding:2px 0;">1.3B dense video generation weights; trainable on 1-2 GPUs</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-video-moe-30b-a3b</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-video-moe-30b-a3b">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-video-moe-30b-a3b">🤖</a></td><td valign="top" style="padding:2px 0;">30B MoE (3B active) video generation weights; training requires 8x80GB or more</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-world-fast</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-world-fast">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-world-fast">🤖</a></td><td valign="top" style="padding:2px 0;">Distilled few-step world model checkpoint (16 transformer shards); its VAE/T5 are reused from lingbot-world-base-cam, and inference must use the Flow_Unipc sampler</td></tr></table> |
|
||||
| Phantom | Video | Incremental weights for multi-subject reference video generation; based on Wan2.1-T2V | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">1.3B version. Officially released as .pth; place in Personalized_Model and reference via transformer_path in predict file</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">14B version. Officially released as sharded safetensors</td></tr></table> |
|
||||
| Qwen-Image | Image | Official text-to-image and image-editing weights; supports baseline and LoRA training | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image">🤖</a></td><td valign="top" style="padding:2px 0;">文生图基础权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2512">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2512">🤖</a></td><td valign="top" style="padding:2px 0;">Updated text-to-image version</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit-2509</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit-2509">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑更新版本</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Layered</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Layered">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Layered">🤖</a></td><td valign="top" style="padding:2px 0;">Image layer-decomposition weights; splits an image into multiple editable RGBA layers</td></tr></table> |
|
||||
| Qwen-Image-2.1 | Image | Official next-generation text-to-image weights; single-stream block-causal transformer with prefix KV cache | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">Single-stream block-causal transformer; supports full-parameter training, prefix KV cache speeds up inference</td></tr></table> |
|
||||
| Qwen-Image ControlNet | Image | Image controlled generation; supports Canny, Depth, Pose, MLSD, and Scribble | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for Qwen-Image-2512, supporting multiple control conditions such as Canny, Depth, Pose, MLSD, Scribble, etc.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">Equivalent ControlNet provided by InstantX</td></tr></table> |
|
||||
| Z-Image | Image | Official text-to-image weights | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image">🤖</a></td><td valign="top" style="padding:2px 0;">基础版</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image-Turbo">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo">🤖</a></td><td valign="top" style="padding:2px 0;">加速版</td></tr></table> |
|
||||
| Z-Image-Fun | Image | ControlNet and distillation LoRA trained by this project on Z-Image; supports Canny, Depth, Pose, MLSD, Scribble, and Gray | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for Z-Image. Compared to the first version, it adds to more layers and has been trained for a longer period. It supports multiple control conditions including Canny, Depth, Pose, MLSD, Scribble and Gray.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for Z-Image-Turbo, supporting multiple control conditions such as Canny, Depth, Pose, MLSD, etc.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for Z-Image-Turbo. Compared to the first version, it adds to more layers and has been trained for a longer period. It supports multiple control conditions including Canny, Depth, Pose, MLSD, and more.</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Lora-Distill</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill">🤖</a></td><td valign="top" style="padding:2px 0;">This is a Distill LoRA for Z-Image that distills both steps and CFG. This model does not require CFG and uses 8 steps for inference.</td></tr></table> |
|
||||
| Flux | Image | Official FLUX.1/FLUX.2 weights and the ControlNet trained by this project | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.1-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.1-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev">🤖</a></td><td valign="top" style="padding:2px 0;">文生图与图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.2-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev">🤖</a></td><td valign="top" style="padding:2px 0;">第二代官方权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">ControlNet weights for FLUX.2-dev</td></tr></table> |
|
||||
| ERNIE-Image | Image | Official Baidu text-to-image weights | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">ERNIE-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/baidu/ERNIE-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PaddlePaddle/ERNIE-Image">🤖</a></td><td valign="top" style="padding:2px 0;">Official ERNIE-Image text-to-image weights</td></tr></table> |
|
||||
| Lens | Image | Official Microsoft camera-control weights | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Lens</td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/microsoft/Lens">🤖</a></td><td valign="top" style="padding:2px 0;">Official Lens camera-control weights</td></tr></table> |
|
||||
| Auxiliary Models | - | Non-generative models used for reward alignment, data annotation, and fast decoding | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">HPSv3</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/MizzenAI/HPSv3">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/MizzenAI/HPSv3">🤖</a></td><td valign="top" style="padding:2px 0;">Scoring model used in reward backpropagation</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen2-VL-7B-Instruct</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen2-VL-7B-Instruct">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen2-VL-7B-Instruct">🤖</a></td><td valign="top" style="padding:2px 0;">Multimodal encoder used in the video captioning pipeline</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">taew2_1 / taew2_2</td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">Tiny AutoEncoders (~20 MB) sharing the latent spaces of the Wan2.1 / Wan2.2 VAEs, ~100x faster decoding for previews and low-memory generation; weights from <a href="https://github.com/madebyollin/taehv">madebyollin/taehv</a></td></tr></table> |
|
||||
|
||||
> Notes:
|
||||
> - Audio-driven and reference models (FantasyTalking, InfiniteTalk, Phantom, TaoMate-H3) are incremental weights and must be used together with the corresponding base video weights and audio encoder.
|
||||
> - The TurboWan weights released by the TurboDiffusion scheme are listed above; other distillation schemes such as Flex-Forcing and PDD have no publicly released weights — train them following `scripts/{model_name}/README_TRAIN*.md` and then fill the resulting path into `transformer_path`.
|
||||
> - Weight names map one-to-one to folder names under `models/Diffusion_Transformer/`. Weights within the same family are not interchangeable; choose according to the inference task. If a weight is not listed here, it is either produced by this project or should be obtained from the upstream official repository.
|
||||
|
||||
# IV. Video Works
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-InP && Wan2.1-Fun-V1.1-1.3B-InP
|
||||
|
||||
@@ -179,6 +409,7 @@ Put the models into the ComfyUI weights folder `ComfyUI/models/Fun_Models/`:
|
||||
### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
|
||||
|
||||
Generic Control Video + Reference Image:
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
@@ -193,6 +424,7 @@ Generic Control Video + Reference Image:
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-1.3B-Control
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
@@ -206,11 +438,12 @@ Generic Control Video + Reference Image:
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
@@ -222,7 +455,7 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
@@ -236,6 +469,7 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
@@ -262,6 +496,7 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<td>
|
||||
Pan Right
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload loop></video>
|
||||
@@ -272,6 +507,7 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
Pan Down
|
||||
@@ -282,6 +518,7 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<td>
|
||||
Pan Up + Pan Right
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload loop></video>
|
||||
@@ -368,6 +605,7 @@ Resolution-512
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
A young woman with beautiful clear eyes and blonde hair, wearing white clothes and twisting her body, with the camera focused on her face. High quality, masterpiece, best quality, high resolution, ultra-fine, dreamlike.
|
||||
@@ -392,299 +630,7 @@ Resolution-512
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
# How to Use
|
||||
|
||||
<h3 id="video-gen">1. Generation</h3>
|
||||
|
||||
#### a. GPU Memory Optimization
|
||||
Since Wan2.1 has a very large number of parameters, we need to consider memory optimization strategies to adapt to consumer-grade GPUs. We provide `GPU_memory_mode` for each prediction file, allowing you to choose between `model_cpu_offload`, `model_cpu_offload_and_qfloat8`, and `sequential_cpu_offload`. This solution is also applicable to CogVideoX-Fun generation.
|
||||
|
||||
- `model_cpu_offload`: The entire model is moved to the CPU after use, saving some GPU memory.
|
||||
- `model_cpu_offload_and_qfloat8`: The entire model is moved to the CPU after use, and the transformer model is quantized to float8, saving more GPU memory.
|
||||
- `sequential_cpu_offload`: Each layer of the model is moved to the CPU after use. It is slower but saves a significant amount of GPU memory.
|
||||
|
||||
`qfloat8` may slightly reduce model performance but saves more GPU memory. If you have sufficient GPU memory, it is recommended to use `model_cpu_offload`.
|
||||
|
||||
#### b. Using ComfyUI
|
||||
For details, refer to [ComfyUI README](comfyui/README.md).
|
||||
|
||||
#### c. Running Python Files
|
||||
|
||||
##### i. Single-GPU Inference:
|
||||
|
||||
- **Step 1**: Download the corresponding [weights](#model-zoo) and place them in the `models` folder.
|
||||
- **Step 2**: Use different files for prediction based on the weights and prediction goals. This library currently supports CogVideoX-Fun, Wan2.1, and Wan2.1-Fun. Different models are distinguished by folder names under the `examples` folder, and their supported features vary. Use them accordingly. Below is an example using CogVideoX-Fun:
|
||||
- **Text-to-Video**:
|
||||
- Modify `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_t2v.py`.
|
||||
- Run the file `examples/cogvideox_fun/predict_t2v.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos`.
|
||||
- **Image-to-Video**:
|
||||
- Modify `validation_image_start`, `validation_image_end`, `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_i2v.py`.
|
||||
- `validation_image_start` is the starting image of the video, and `validation_image_end` is the ending image of the video.
|
||||
- Run the file `examples/cogvideox_fun/predict_i2v.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos_i2v`.
|
||||
- **Video-to-Video**:
|
||||
- Modify `validation_video`, `validation_image_end`, `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_v2v.py`.
|
||||
- `validation_video` is the reference video for video-to-video generation. You can use the following demo video: [Demo Video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/play_guitar.mp4).
|
||||
- Run the file `examples/cogvideox_fun/predict_v2v.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos_v2v`.
|
||||
- **Controlled Video Generation (Canny, Pose, Depth, etc.)**:
|
||||
- Modify `control_video`, `validation_image_end`, `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_v2v_control.py`.
|
||||
- `control_video` is the control video extracted using operators such as Canny, Pose, or Depth. You can use the following demo video: [Demo Video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/pose.mp4).
|
||||
- Run the file `examples/cogvideox_fun/predict_v2v_control.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos_v2v_control`.
|
||||
- **Step 3**: If you want to integrate other backbones or Loras trained by yourself, modify `lora_path` and relevant paths in `examples/{model_name}/predict_t2v.py` or `examples/{model_name}/predict_i2v.py` as needed.
|
||||
|
||||
##### ii. Multi-GPU Inference:
|
||||
When using multi-GPU inference, please make sure to install the xfuser. We recommend installing xfuser==0.4.2 and yunchang==0.6.2.
|
||||
```
|
||||
pip install xfuser==0.4.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
pip install yunchang==0.6.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
```
|
||||
|
||||
Please ensure that the product of `ulysses_degree` and `ring_degree` equals the number of GPUs being used. For example, if you are using 8 GPUs, you can set `ulysses_degree=2` and `ring_degree=4`, or alternatively `ulysses_degree=4` and `ring_degree=2`.
|
||||
|
||||
- `ulysses_degree` performs parallelization after splitting across the heads.
|
||||
- `ring_degree` performs parallelization after splitting across the sequence.
|
||||
|
||||
Compared to `ulysses_degree`, `ring_degree` incurs higher communication costs. Therefore, when setting these parameters, you should take into account both the sequence length and the number of heads in the model.
|
||||
|
||||
Let’s take 8-GPU parallel inference as an example:
|
||||
|
||||
- **For Wan2.1-Fun-V1.1-14B-InP**, which has 40 heads, `ulysses_degree` should be set to a divisor of 40 (e.g., 2, 4, 8, etc.). Thus, when using 8 GPUs for parallel inference, you can set `ulysses_degree=8` and `ring_degree=1`.
|
||||
|
||||
- **For Wan2.1-Fun-V1.1-1.3B-InP**, which has 12 heads, `ulysses_degree` should be set to a divisor of 12 (e.g., 2, 4, etc.). Thus, when using 8 GPUs for parallel inference, you can set `ulysses_degree=4` and `ring_degree=2`.
|
||||
|
||||
After setting the parameters, run the following command for parallel inference:
|
||||
|
||||
```sh
|
||||
torchrun --nproc-per-node=8 examples/wan2.1_fun/predict_t2v.py
|
||||
```
|
||||
|
||||
#### d. Using the Web UI
|
||||
The web UI supports text-to-video, image-to-video, video-to-video, and controlled video generation (Canny, Pose, Depth, etc.). This library currently supports CogVideoX-Fun, Wan2.1, and Wan2.1-Fun. Different models are distinguished by folder names under the `examples` folder, and their supported features vary. Use them accordingly. Below is an example using CogVideoX-Fun:
|
||||
|
||||
- **Step 1**: Download the corresponding [weights](#model-zoo) and place them in the `models` folder.
|
||||
- **Step 2**: Run the file `examples/cogvideox_fun/app.py` to access the Gradio interface.
|
||||
- **Step 3**: Select the generation model on the page, fill in `prompt`, `neg_prompt`, `guidance_scale`, and `seed`, click "Generate," and wait for the results. The generated videos will be saved in the `sample` folder.
|
||||
|
||||
### 2. Model Training
|
||||
A complete model training pipeline should include data preprocessing and Video DiT training. The training process for different models is similar, and the data formats are also similar:
|
||||
|
||||
<h4 id="data-preprocess">a. data preprocessing</h4>
|
||||
|
||||
We have provided a simple demo of training the Lora model through image data, which can be found in the [wiki](https://github.com/aigc-apps/CogVideoX-Fun/wiki/Training-Lora) for details.
|
||||
|
||||
A complete data preprocessing link for long video segmentation, cleaning, and description can refer to [README](cogvideox/video_caption/README.md) in the video captions section.
|
||||
|
||||
If you want to train a text to image and video generation model. You need to arrange the dataset in this format.
|
||||
|
||||
```
|
||||
📦 project/
|
||||
├── 📂 datasets/
|
||||
│ ├── 📂 internal_datasets/
|
||||
│ ├── 📂 train/
|
||||
│ │ ├── 📄 00000001.mp4
|
||||
│ │ ├── 📄 00000002.jpg
|
||||
│ │ └── 📄 .....
|
||||
│ └── 📄 json_of_internal_datasets.json
|
||||
```
|
||||
|
||||
The json_of_internal_datasets.json is a standard JSON file. The file_path in the json can to be set as relative path, as shown in below:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "train/00000001.mp4",
|
||||
"text": "A group of young men in suits and sunglasses are walking down a city street.",
|
||||
"type": "video"
|
||||
},
|
||||
{
|
||||
"file_path": "train/00000002.jpg",
|
||||
"text": "A group of young men in suits and sunglasses are walking down a city street.",
|
||||
"type": "image"
|
||||
},
|
||||
.....
|
||||
]
|
||||
```
|
||||
|
||||
You can also set the path as absolute path as follow:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "/mnt/data/videos/00000001.mp4",
|
||||
"text": "A group of young men in suits and sunglasses are walking down a city street.",
|
||||
"type": "video"
|
||||
},
|
||||
{
|
||||
"file_path": "/mnt/data/train/00000001.jpg",
|
||||
"text": "A group of young men in suits and sunglasses are walking down a city street.",
|
||||
"type": "image"
|
||||
},
|
||||
.....
|
||||
]
|
||||
```
|
||||
|
||||
<h4 id="dit-train">b. Video DiT training </h4>
|
||||
|
||||
If the data format is relative path during data preprocessing, please set ```scripts/{model_name}/train.sh``` as follow.
|
||||
```
|
||||
export DATASET_NAME="datasets/internal_datasets/"
|
||||
export DATASET_META_NAME="datasets/internal_datasets/json_of_internal_datasets.json"
|
||||
```
|
||||
|
||||
If the data format is absolute path during data preprocessing, please set ```scripts/train.sh``` as follow.
|
||||
```
|
||||
export DATASET_NAME=""
|
||||
export DATASET_META_NAME="/mnt/data/json_of_internal_datasets.json"
|
||||
```
|
||||
|
||||
Then, we run scripts/train.sh.
|
||||
```sh
|
||||
sh scripts/train.sh
|
||||
```
|
||||
|
||||
For details on some parameter settings:
|
||||
Wan2.1-Fun can be found in [Readme Train](scripts/wan2.1_fun/README_TRAIN.md) and [Readme Lora](scripts/wan2.1_fun/README_TRAIN_LORA.md).
|
||||
Wan2.1 can be found in [Readme Train](scripts/wan2.1/README_TRAIN.md) and [Readme Lora](scripts/wan2.1/README_TRAIN_LORA.md).
|
||||
CogVideoX-Fun can be found in [Readme Train](scripts/cogvideox_fun/README_TRAIN.md) and [Readme Lora](scripts/cogvideox_fun/README_TRAIN_LORA.md).
|
||||
|
||||
|
||||
# Model zoo
|
||||
## 1. Wan2.2-Fun
|
||||
|
||||
| Name | Storage Size | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.2-Fun-A14B-InP | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-InP) | Wan2.2-Fun-14B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
|
||||
| Wan2.2-Fun-A14B-Control | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control)| Wan2.2-Fun-14B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support. |
|
||||
| Wan2.2-Fun-A14B-Control-Camera | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control-Camera)| Wan2.2-Fun-14B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
| Wan2.2-VACE-Fun-A14B | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-VACE-Fun-A14B) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-VACE-Fun-A14B) | Control weights for Wan2.2 trained using the VACE scheme (based on the base model Wan2.2-T2V-A14B), supporting various control conditions such as Canny, Depth, Pose, MLSD, trajectory control, etc. It supports video generation by specifying the subject. It supports multi-resolution (512, 768, 1024) video prediction, and is trained with 81 frames at 16 FPS. It also supports multi-language prediction. |
|
||||
| Wan2.2-Fun-5B-InP | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-InP) | Wan2.2-Fun-5B text-to-video weights trained at 121 frames, 24 FPS, supporting first/last frame prediction. |
|
||||
| Wan2.2-Fun-5B-Control | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control)| Wan2.2-Fun-5B video control weights, supporting control conditions like Canny, Depth, Pose, MLSD, and trajectory control. Trained at 121 frames, 24 FPS, with multilingual prediction support. |
|
||||
| Wan2.2-Fun-5B-Control-Camera | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control-Camera)| Wan2.2-Fun-5B camera lens control weights. Trained at 121 frames, 24 FPS, with multilingual prediction support. |
|
||||
|
||||
|
||||
## 2. Wan2.2
|
||||
|
||||
| Name | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|
|
||||
| Wan2.2-TI2V-5B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-TI2V-5B) | Wan2.2-5B Text-to-Video Weights |
|
||||
| Wan2.2-T2V-14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-T2V-A14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-T2V-A14B) | Wan2.2-14B Text-to-Video Weights |
|
||||
| Wan2.2-I2V-A14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-I2V-A14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-I2V-A14B) | Wan2.2-I2V-A14B Image-to-Video Weights |
|
||||
|
||||
## 3. Wan2.1-Fun
|
||||
|
||||
V1.1:
|
||||
| Name | Storage Size | Hugging Face | Model Scope | Description |
|
||||
|------|--------------|--------------|-------------|-------------|
|
||||
| Wan2.1-Fun-V1.1-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP) | Wan2.1-Fun-V1.1-1.3B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
|
||||
| Wan2.1-Fun-V1.1-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP) | Wan2.1-Fun-V1.1-14B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control) | Wan2.1-Fun-V1.1-1.3B video control weights support various control conditions such as Canny, Depth, Pose, MLSD, etc., supports reference image + control condition-based control, and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control) | Wan2.1-Fun-V1.1-14B video control weights support various control conditions such as Canny, Depth, Pose, MLSD, etc., supports reference image + control condition-based control, and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control-Camera | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control-Camera) | Wan2.1-Fun-V1.1-1.3B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
| Wan2.1-Fun-V1.1-14B-Control-Camera | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control-Camera) | Wan2.1-Fun-V1.1-14B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
|
||||
V1.0:
|
||||
| Name | Storage Space | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-InP) | Wan2.1-Fun-1.3B text-to-video weights, trained at multiple resolutions, supporting start and end frame prediction. |
|
||||
| Wan2.1-Fun-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP) | Wan2.1-Fun-14B text-to-video weights, trained at multiple resolutions, supporting start and end frame prediction. |
|
||||
| Wan2.1-Fun-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-Control) | Wan2.1-Fun-1.3B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support. |
|
||||
| Wan2.1-Fun-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-Control) | Wan2.1-Fun-14B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support. |
|
||||
|
||||
## 4. Wan2.1
|
||||
|
||||
| Name | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|
|
||||
| Wan2.1-T2V-1.3B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-1.3B) | Wanxiang 2.1-1.3B text-to-video weights |
|
||||
| Wan2.1-T2V-14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-14B) | Wanxiang 2.1-14B text-to-video weights |
|
||||
| Wan2.1-I2V-14B-480P | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-480P) | Wanxiang 2.1-14B-480P image-to-video weights |
|
||||
| Wan2.1-I2V-14B-720P| [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | Wanxiang 2.1-14B-720P image-to-video weights |
|
||||
|
||||
## 5. FantasyTalking
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-I2V-14B-720P | - | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | Wan 2.1-14B-720P image-to-video model weights |
|
||||
| Wav2Vec | - | [🤗Link](https://huggingface.co/facebook/wav2vec2-base-960h) | [😄Link](https://modelscope.cn/models/AI-ModelScope/wav2vec2-base-960h) | Wav2Vec model; place inside the Wan2.1-I2V-14B-720P folder and rename to `audio_encoder` |
|
||||
| FantasyTalking model | - | [🤗Link](https://huggingface.co/acvlab/FantasyTalking/) | [😄Link](https://www.modelscope.cn/models/amap_cvlab/FantasyTalking/) | Official audio-conditioned weights |
|
||||
|
||||
## 6. Qwen-Image
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image | [🤗Link](https://huggingface.co/Qwen/Qwen-Image) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image) | Official Qwen-Image weights |
|
||||
| Qwen-Image-Edit | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit) | Official Qwen-Image-Edit weights |
|
||||
| Qwen-Image-Edit-2509 | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit-2509) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509) | Official Qwen-Image-Edit-2509 weights |
|
||||
|
||||
## 7. Qwen-Image-Fun
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image-2512-Fun-Controlnet-Union | - | [🤗Link](https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union) | [😄Link](https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union) | ControlNet weights for Qwen-Image-2512, supporting multiple control conditions such as Canny, Depth, Pose, MLSD, Scribble, etc. |
|
||||
|
||||
## 8. Z-Image
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image | [🤗Link](https://huggingface.co/Tongyi-MAI/Z-Image) | [😄Link](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image) | Official weights for Z-Image |
|
||||
| Z-Image-Turbo | [🤗Link](https://huggingface.co/Tongyi-MAI/Z-Image-Turbo) | [😄Link](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo) | Official weights for Z-Image-Turbo |
|
||||
|
||||
## 9. Z-Image-Fun
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image-Fun-Controlnet-Union-2.1 | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1) | ControlNet weights for Z-Image. Compared to the first version, it adds to more layers and has been trained for a longer period. It supports multiple control conditions including Canny, Depth, Pose, MLSD, Scribble and Gray. |
|
||||
| Z-Image-Fun-Lora-Distill | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill) | This is a Distill LoRA for Z-Image that distills both steps and CFG. This model does not require CFG and uses 8 steps for inference. |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union) | ControlNet weights for Z-Image-Turbo, supporting multiple control conditions such as Canny, Depth, Pose, MLSD, etc. |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union-2.1 | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | ControlNet weights for Z-Image-Turbo. Compared to the first version, it adds to more layers and has been trained for a longer period. It supports multiple control conditions including Canny, Depth, Pose, MLSD, and more. |
|
||||
|
||||
## 10. Flux
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| FLUX.1-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.1-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev) | Official FLUX.1-dev weights |
|
||||
| FLUX.2-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.2-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev) | Official FLUX.2-dev weights |
|
||||
|
||||
## 11. Flux-Fun
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Flux.2-dev-Fun-Controlnet-Union | - | [🤗Link](https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union) | [😄Link](https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union) | Flux.2-dev control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc. |
|
||||
|
||||
## 12. HunyuanVideo
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| HunyuanVideo | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo) | - | HunyuanVideo-diffusers weights |
|
||||
| HunyuanVideo-I2V | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo-I2V) | - | HunyuanVideo-I2V-diffusers weights |
|
||||
|
||||
## 13. CogVideoX-Fun
|
||||
|
||||
V1.5:
|
||||
|
||||
| Name | Storage Space | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.5-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-5b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024) and has been trained on 85 frames at a rate of 8 frames per second. |
|
||||
| CogVideoX-Fun-V1.5-Reward-LoRAs | - | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs) | The official reward backpropagation technology model optimizes the videos generated by CogVideoX-Fun-V1.5 to better match human preferences. |
|
||||
|
||||
V1.1:
|
||||
|
||||
| Name | Storage Space | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.1-2b-InP | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. |
|
||||
| CogVideoX-Fun-V1.1-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Noise has been added to the reference image, and the amplitude of motion is greater compared to V1.0. |
|
||||
| CogVideoX-Fun-V1.1-2b-Pose | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Pose) | Our official pose-control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second.|
|
||||
| CogVideoX-Fun-V1.1-2b-Control | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Control) | Our official control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Supporting various control conditions such as Canny, Depth, Pose, MLSD, etc.|
|
||||
| CogVideoX-Fun-V1.1-5b-Pose | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Pose) | Our official pose-control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second.|
|
||||
| CogVideoX-Fun-V1.1-5b-Control | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Control) | Our official control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Supporting various control conditions such as Canny, Depth, Pose, MLSD, etc.|
|
||||
| CogVideoX-Fun-V1.1-Reward-LoRAs | - | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-Reward-LoRAs) | The official reward backpropagation technology model optimizes the videos generated by CogVideoX-Fun-V1.1 to better match human preferences. |
|
||||
|
||||
<details>
|
||||
<summary>(Obsolete) V1.0:</summary>
|
||||
|
||||
| Name | Storage Space | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-2b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. |
|
||||
| CogVideoX-Fun-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP)| [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-5b-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. |
|
||||
</details>
|
||||
|
||||
# Reference
|
||||
# V. References
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
|
||||
- Wan2.1: https://github.com/Wan-Video/Wan2.1/
|
||||
@@ -700,7 +646,7 @@ V1.1:
|
||||
- ComfyUI-CameraCtrl-Wrapper: https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper
|
||||
- CameraCtrl: https://github.com/hehao13/CameraCtrl
|
||||
|
||||
# Citation
|
||||
# VI. Citation
|
||||
|
||||
If you use VideoX-Fun in your research or project, please cite it as follows:
|
||||
|
||||
@@ -714,7 +660,7 @@ If you use VideoX-Fun in your research or project, please cite it as follows:
|
||||
}
|
||||
```
|
||||
|
||||
# Limitations and Risks
|
||||
# VII. Limitations and Risks
|
||||
|
||||
- Generated videos may have artifacts or quality issues, especially in complex scenes.
|
||||
- The model may struggle with fine details, text rendering, or specific artistic styles.
|
||||
@@ -725,7 +671,7 @@ If you use VideoX-Fun in your research or project, please cite it as follows:
|
||||
|
||||
We encourage responsible use and recommend implementing safeguards in production environments.
|
||||
|
||||
# License
|
||||
# VIII. License
|
||||
This project is licensed under the [Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE).
|
||||
|
||||
The CogVideoX-2B model (including its corresponding Transformers module and VAE module) is released under the [Apache 2.0 License](LICENSE).
|
||||
|
||||
+291
-345
@@ -11,21 +11,21 @@ Wan-Fun:
|
||||
[English](./README.md) | [简体中文](./README_zh-CN.md) | 日本語
|
||||
|
||||
# 目次
|
||||
- [紹介](#紹介)
|
||||
- [クイックスタート](#クイックスタート)
|
||||
- [ビデオ結果](#ビデオ結果)
|
||||
- [使用方法](#使用方法)
|
||||
- [モデルの場所](#モデルの場所)
|
||||
- [参考文献](#参考文献)
|
||||
- [引用](#引用)
|
||||
- [制限とリスク](#制限とリスク)
|
||||
- [ライセンス](#ライセンス)
|
||||
- [一、紹介](#一紹介)
|
||||
- [二、クイックスタートと使用](#二クイックスタートと使用)
|
||||
- [1. 環境準備](#1-環境準備)
|
||||
- [2. 推論生成](#2-推論生成)
|
||||
- [3. モデルのトレーニング](#3-モデルのトレーニング)
|
||||
- [三、サポート済みモデル](#三サポート済みモデル)
|
||||
- [四、ビデオ作品](#四ビデオ作品)
|
||||
- [五、参考文献](#五参考文献)
|
||||
- [六、引用](#六引用)
|
||||
- [七、制限とリスク](#七制限とリスク)
|
||||
- [八、ライセンス](#八ライセンス)
|
||||
|
||||
# 紹介
|
||||
# 一、紹介
|
||||
VideoX-Funはビデオ生成のパイプラインであり、AI画像やビデオの生成、Diffusion TransformerのベースラインモデルとLoraモデルのトレーニングに使用できます。我々は、すでに学習済みのベースラインモデルから直接予測を行い、異なる解像度、秒数、FPSのビデオを生成することをサポートしています。また、ユーザーが独自のベースラインモデルやLoraモデルをトレーニングし、特定のスタイル変換を行うこともサポートしています。
|
||||
|
||||
異なるプラットフォームからのクイックスタートをサポートします。詳細は[クイックスタート](#クイックスタート)を参照してください。
|
||||
|
||||
新機能:
|
||||
- Wan 2.2シリーズモデル、Wan-VACE制御モデル、Fantasy Talkingデジタルヒューマンモデル、Qwen-Image、Flux画像生成モデルなどのサポートを追加しました。[2025.10.16]
|
||||
- Wan2.1-Fun-V1.1バージョンを更新:14Bと1.3BモデルのControl+参照画像モデルをサポート、カメラ制御にも対応。さらに、Inpaintモデルを再訓練し、性能が向上しました。[2025.04.25]
|
||||
@@ -44,20 +44,44 @@ VideoX-Funはビデオ生成のパイプラインであり、AI画像やビデ
|
||||
私たちのUIインターフェースは次のとおりです:
|
||||

|
||||
|
||||
# クイックスタート
|
||||
### 1. クラウド使用: AliyunDSW/Docker
|
||||
#### a. AliyunDSWから
|
||||
# 二、クイックスタートと使用
|
||||
|
||||
<a id="quick-start"></a>
|
||||
|
||||
## 1. 環境準備
|
||||
|
||||
### 1.1 クラウド使用: AliyunDSW
|
||||
|
||||
DSWには無料のGPU時間があり、ユーザーは一度申請でき、申請後3か月間有効です。
|
||||
|
||||
Aliyunは[Freetier](https://free.aliyun.com/?product=9602825&crowd=enterprise&spm=5176.28055625.J_5831864660.1.e939154aRgha4e&scm=20140722.M_9974135.P_110.MO_1806-ID_9974135-MID_9974135-CID_30683-ST_8512-V_1)で無料のGPU時間を提供しています。取得してAliyun PAI-DSWで使用し、5分以内にCogVideoX-Funを開始できます!
|
||||
|
||||
[](https://gallery.pai-ml.com/#/preview/deepLearning/cv/cogvideox_fun)
|
||||
|
||||
#### b. ComfyUIから
|
||||
私たちのComfyUIは次のとおりです。詳細は[ComfyUI README](comfyui/README.md)を参照してください。
|
||||

|
||||
### 1.2 ローカル依存のインストール
|
||||
|
||||
以下の環境でこのライブラリの実行を確認しています:
|
||||
|
||||
Windowsの詳細:
|
||||
- OS: Windows 10
|
||||
- python: python3.10 & python3.11
|
||||
- pytorch: torch2.2.0
|
||||
- CUDA: 11.8 & 12.1
|
||||
- CUDNN: 8+
|
||||
- GPU: Nvidia-3060 12G & Nvidia-3090 24G
|
||||
|
||||
Linuxの詳細:
|
||||
- OS: Ubuntu 20.04, CentOS
|
||||
- python: python3.10 & python3.11
|
||||
- pytorch: torch2.2.0
|
||||
- CUDA: 11.8 & 12.1
|
||||
- CUDNN: 8+
|
||||
- GPU:Nvidia-V100 16G & Nvidia-A10 24G & Nvidia-A100 40G & Nvidia-A100 80G
|
||||
|
||||
重みを保存するために約60GBのディスクスペースが必要です。確認してください!
|
||||
|
||||
### 1.3 Dockerの使用
|
||||
|
||||
#### c. Dockerから
|
||||
Dockerを使用する場合、マシンにグラフィックスカードドライバとCUDA環境が正しくインストールされていることを確認してください。
|
||||
|
||||
次のコマンドをこの方法で実行します:
|
||||
@@ -89,30 +113,9 @@ mkdir models/Personalized_Model
|
||||
# https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP
|
||||
```
|
||||
|
||||
### 2. ローカルインストール: 環境チェック/ダウンロード/インストール
|
||||
#### a. 環境チェック
|
||||
以下の環境でこのライブラリの実行を確認しています:
|
||||
### 1.4 重みの配置
|
||||
|
||||
Windowsの詳細:
|
||||
- OS: Windows 10
|
||||
- python: python3.10 & python3.11
|
||||
- pytorch: torch2.2.0
|
||||
- CUDA: 11.8 & 12.1
|
||||
- CUDNN: 8+
|
||||
- GPU: Nvidia-3060 12G & Nvidia-3090 24G
|
||||
|
||||
Linuxの詳細:
|
||||
- OS: Ubuntu 20.04, CentOS
|
||||
- python: python3.10 & python3.11
|
||||
- pytorch: torch2.2.0
|
||||
- CUDA: 11.8 & 12.1
|
||||
- CUDNN: 8+
|
||||
- GPU:Nvidia-V100 16G & Nvidia-A10 24G & Nvidia-A100 40G & Nvidia-A100 80G
|
||||
|
||||
重みを保存するために約60GBのディスクスペースが必要です。確認してください!
|
||||
|
||||
#### b. 重み
|
||||
[重み](#model-zoo)を指定されたパスに配置することをお勧めします:
|
||||
[重み](#三サポート済みモデル)を指定されたパスに配置することをお勧めします:
|
||||
|
||||
**ComfyUIを通じて**:
|
||||
モデルをComfyUIの重みフォルダ `ComfyUI/models/Fun_Models/` に入れます:
|
||||
@@ -138,7 +141,234 @@ Linuxの詳細:
|
||||
│ └── あなたのトレーニング済みのトランスフォーマーモデル / あなたのトレーニング済みのLoraモデル(UIロード用)
|
||||
```
|
||||
|
||||
# ビデオ結果
|
||||
## 2. 推論生成
|
||||
|
||||
<a id="video-gen"></a>
|
||||
|
||||
ビデオモデルと画像モデルの推論入口は完全に一致しており、`examples/{model_name}/`下のスクリプトまたはUIから実行します。
|
||||
|
||||
### 2.1 入口の選択
|
||||
|
||||
| 使用入口 | 適用シーン | 設定粒度 |
|
||||
|--|--|--|
|
||||
| Pythonファイル | バッチ生成、スクリプト内でパラメータを調整 | 全パラメータ |
|
||||
| WebUI | 対話的な体験、モデルの迅速な切り替え | よく使うパラメータのみ |
|
||||
| ComfyUI | 既存のComfyUIワークフロー | ノードパラメータ |
|
||||
|
||||
表:推論入口の選択
|
||||
|
||||
### 2.2 顕存節約方案
|
||||
|
||||
Wan2.1のパラメータが非常に大きいため、GPUメモリを節約し、コンシューマー向けGPUに適応させる必要があります。各予測ファイルには`GPU_memory_mode`を提供しており、`model_cpu_offload`、`model_cpu_offload_and_qfloat8`、`sequential_cpu_offload`の中から選択できます。この方法はCogVideoX-Funの生成にも適用されます。
|
||||
|
||||
- `model_cpu_offload`: モデル全体が使用後にCPUに移動し、一部のGPUメモリを節約します。
|
||||
- `model_cpu_offload_and_qfloat8`: モデル全体が使用後にCPUに移動し、Transformerモデルに対してfloat8の量子化を行い、より多くのGPUメモリを節約します。
|
||||
- `sequential_cpu_offload`: モデルの各層が使用後にCPUに移動します。速度は遅くなりますが、大量のGPUメモリを節約します。
|
||||
|
||||
`qfloat8`はモデルの性能を部分的に低下させる可能性がありますが、より多くのGPUメモリを節約できます。十分なGPUメモリがある場合は、`model_cpu_offload`の使用をお勧めします。
|
||||
|
||||
### 2.3 Pythonファイルから
|
||||
|
||||
##### i. 単一GPUでの推論:
|
||||
|
||||
- ステップ1: 対応する[重み](#三サポート済みモデル)をダウンロードし、`models`フォルダに配置します。
|
||||
- ステップ2: 異なる重みと予測目標に基づいて、異なるファイルを使用して予測を行います。現在、このライブラリはCogVideoX-Fun、Wan2.1、およびWan2.1-Funをサポートしています。`examples`フォルダ内のフォルダ名で区別され、異なるモデルがサポートする機能が異なりますので、状況に応じて区別してください。以下はCogVideoX-Funを例として説明します。
|
||||
- テキストからビデオ:
|
||||
- `examples/cogvideox_fun/predict_t2v.py`ファイルで`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- 次に、`examples/cogvideox_fun/predict_t2v.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos`フォルダに保存されます。
|
||||
- 画像からビデオ:
|
||||
- `examples/cogvideox_fun/predict_i2v.py`ファイルで`validation_image_start`、`validation_image_end`、`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- `validation_image_start`はビデオの開始画像、`validation_image_end`はビデオの終了画像です。
|
||||
- 次に、`examples/cogvideox_fun/predict_i2v.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos_i2v`フォルダに保存されます。
|
||||
- ビデオからビデオ:
|
||||
- `examples/cogvideox_fun/predict_v2v.py`ファイルで`validation_video`、`validation_image_end`、`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- `validation_video`はビデオ生成のための参照ビデオです。以下のデモビデオを使用して実行できます:[デモビデオ](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/play_guitar.mp4)
|
||||
- 次に、`examples/cogvideox_fun/predict_v2v.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos_v2v`フォルダに保存されます。
|
||||
- 通常の制御付きビデオ生成(Canny、Pose、Depthなど):
|
||||
- `examples/cogvideox_fun/predict_v2v_control.py`ファイルで`control_video`、`validation_image_end`、`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- `control_video`は、Canny、Pose、Depthなどの演算子で抽出された制御用ビデオです。以下のデモビデオを使用して実行できます:[デモビデオ](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/pose.mp4)
|
||||
- 次に、`examples/cogvideox_fun/predict_v2v_control.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos_v2v_control`フォルダに保存されます。
|
||||
- ステップ3: 自分でトレーニングした他のバックボーンやLoraを組み合わせたい場合は、必要に応じて`examples/{model_name}/predict_t2v.py`や`examples/{model_name}/predict_i2v.py`、`lora_path`を修正します。
|
||||
|
||||
##### ii. 複数GPUでの推論:
|
||||
多カードでの推論を行う際は、xfuserリポジトリのインストールに注意してください。xfuser==0.4.2 と yunchang==0.6.2 のインストールが推奨されます。
|
||||
```
|
||||
pip install xfuser==0.4.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
pip install yunchang==0.6.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
```
|
||||
|
||||
`ulysses_degree` と `ring_degree` の積が使用する GPU 数と一致することを確認してください。たとえば、8つのGPUを使用する場合、`ulysses_degree=2` と `ring_degree=4`、または `ulysses_degree=4` と `ring_degree=2` を設定することができます。
|
||||
|
||||
- `ulysses_degree` はヘッド(head)に分割した後の並列化を行います。
|
||||
- `ring_degree` はシーケンスに分割した後の並列化を行います。
|
||||
|
||||
`ring_degree` は `ulysses_degree` よりも通信コストが高いため、これらのパラメータを設定する際には、シーケンス長とモデルのヘッド数を考慮する必要があります。
|
||||
|
||||
8GPUでの並列推論を例に挙げます:
|
||||
|
||||
- **Wan2.1-Fun-V1.1-14B-InP** はヘッド数が40あります。この場合、`ulysses_degree` は40で割り切れる値(例:2, 4, 8など)に設定する必要があります。したがって、8GPUを使用して並列推論を行う場合、`ulysses_degree=8` と `ring_degree=1` を設定できます。
|
||||
|
||||
- **Wan2.1-Fun-V1.1-1.3B-InP** はヘッド数が12あります。この場合、`ulysses_degree` は12で割り切れる値(例:2, 4など)に設定する必要があります。したがって、8GPUを使用して並列推論を行う場合、`ulysses_degree=4` と `ring_degree=2` を設定できます。
|
||||
|
||||
パラメータの設定が完了したら、以下のコマンドで並列推論を実行してください:
|
||||
|
||||
```sh
|
||||
torchrun --nproc-per-node=8 examples/wan2.1_fun/predict_t2v.py
|
||||
```
|
||||
|
||||
### 2.4 UIインターフェースから
|
||||
|
||||
WebUIは、テキストからビデオ、画像からビデオ、ビデオからビデオ、および通常の制御付きビデオ生成(Canny、Pose、Depthなど)をサポートします。現在、このライブラリはCogVideoX-Fun、Wan2.1、およびWan2.1-Funをサポートしており、`examples`フォルダ内のフォルダ名で区別されています。異なるモデルがサポートする機能が異なるため、状況に応じて区別してください。以下はCogVideoX-Funを例として説明します。
|
||||
|
||||
- ステップ1: 対応する[重み](#三サポート済みモデル)をダウンロードし、`models`フォルダに配置します。
|
||||
- ステップ2: `examples/cogvideox_fun/app.py`ファイルを実行し、Gradioページに入ります。
|
||||
- ステップ3: ページ上で生成モデルを選択し、`prompt`、`neg_prompt`、`guidance_scale`、`seed`などを入力し、「生成」をクリックして結果が生成されるのを待ちます。結果は`sample`フォルダに保存されます。
|
||||
|
||||
### 2.5 ComfyUIから
|
||||
|
||||
詳細は[ComfyUI README](comfyui/README.md)をご覧ください。
|
||||
|
||||
|
||||
## 3. モデルのトレーニング
|
||||
|
||||
完全なモデルトレーニングパイプラインは、データ前処理とVideo DiTトレーニングで構成されます。
|
||||
|
||||
### 3.1 データ前処理
|
||||
|
||||
<a id="data-preprocess"></a>
|
||||
各モデルの訓練ドキュメントは`scripts/{model_name}/`下に統一されています。詳細は[3.3 各モデルの訓練ドキュメント](#33-各モデルの訓練ドキュメント)を参照してください。
|
||||
|
||||
長いビデオのセグメンテーション、クリーニング、説明のための完全なデータ前処理リンクは、ビデオキャプションセクションの[README](videox_fun/video_caption/README.md)を参照してください。
|
||||
|
||||
テキストから画像およびビデオ生成モデルをトレーニングしたい場合。この形式でデータセットを配置する必要があります。
|
||||
|
||||
```
|
||||
📦 project/
|
||||
├── 📂 datasets/
|
||||
│ ├── 📂 internal_datasets/
|
||||
│ ├── 📂 train/
|
||||
│ │ ├── 📄 00000001.mp4
|
||||
│ │ ├── 📄 00000002.jpg
|
||||
│ │ └── 📄 .....
|
||||
│ └── 📄 json_of_internal_datasets.json
|
||||
```
|
||||
|
||||
json_of_internal_datasets.jsonは標準のJSONファイルです。json内のfile_pathは相対パスとして設定できます。以下のように:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "train/00000001.mp4",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "video"
|
||||
},
|
||||
{
|
||||
"file_path": "train/00000002.jpg",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "image"
|
||||
},
|
||||
.....
|
||||
]
|
||||
```
|
||||
|
||||
次のように絶対パスとして設定することもできます:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "/mnt/data/videos/00000001.mp4",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "video"
|
||||
},
|
||||
{
|
||||
"file_path": "/mnt/data/train/00000001.jpg",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "image"
|
||||
},
|
||||
.....
|
||||
]
|
||||
```
|
||||
|
||||
### 3.2 Video DiTのトレーニング
|
||||
|
||||
<a id="dit-train"></a>
|
||||
各モデルの訓練スクリプトと起動shは`scripts/{model_name}/`下にあり、shの名称はタスクによって異なります(例:`train.sh`、`train_lora.sh`、`train_control.sh`、`train_control_distill.sh`など)。ディレクトリ内の実際のファイルを基準としてください。
|
||||
|
||||
データ前処理時にデータ形式が相対パスの場合、```scripts/{model_name}/train.sh```を次のように設定します。
|
||||
```
|
||||
export DATASET_NAME="datasets/internal_datasets/"
|
||||
export DATASET_META_NAME="datasets/internal_datasets/json_of_internal_datasets.json"
|
||||
```
|
||||
|
||||
データ形式が絶対パスの場合、同じスクリプトで次のように設定します(このとき`DATASET_NAME`は空にし、データセットディレクトリのプレフィックスを連結しません)。
|
||||
```
|
||||
export DATASET_NAME=""
|
||||
export DATASET_META_NAME="/mnt/data/json_of_internal_datasets.json"
|
||||
```
|
||||
|
||||
最後に対応するスクリプトを実行します。
|
||||
```sh
|
||||
sh scripts/{model_name}/train.sh
|
||||
```
|
||||
|
||||
### 3.3 各モデルの訓練ドキュメント
|
||||
|
||||
パラメータ設定の詳細について、各モデルの訓練ドキュメントは`scripts/{model_name}/`下に統一されています。
|
||||
|
||||
| モデル | ベーストレーニング | LoRAトレーニング | その他 |
|
||||
|--|--|--|--|
|
||||
| Wan2.1-Fun | [EN](scripts/wan2.1_fun/README_TRAIN.md) / [ZH](scripts/wan2.1_fun/README_TRAIN_zh-CN.md) | [EN](scripts/wan2.1_fun/README_TRAIN_LORA.md) / [ZH](scripts/wan2.1_fun/README_TRAIN_LORA_zh-CN.md) | [Control ZH](scripts/wan2.1_fun/README_TRAIN_CONTROL_zh-CN.md)、[Reward LoRA](scripts/wan2.1_fun/README_TRAIN_REWARD.md) |
|
||||
| Wan2.2 | [EN](scripts/wan2.2/README_TRAIN.md) / [ZH](scripts/wan2.2/README_TRAIN_zh-CN.md) | [EN](scripts/wan2.2/README_TRAIN_LORA.md) / [ZH](scripts/wan2.2/README_TRAIN_LORA_zh-CN.md) | [Distill ZH](scripts/wan2.2/README_TRAIN_DISTILL_zh-CN.md)、[S2V](scripts/wan2.2/README_TRAIN_S2V.md)、[Animate](scripts/wan2.2/README_TRAIN_ANIMATE.md) |
|
||||
| Wan2.2-Fun | [EN](scripts/wan2.2_fun/README_TRAIN.md) / [ZH](scripts/wan2.2_fun/README_TRAIN_zh-CN.md) | [EN](scripts/wan2.2_fun/README_TRAIN_LORA.md) / [ZH](scripts/wan2.2_fun/README_TRAIN_LORA_zh-CN.md) | [Control LoRA ZH](scripts/wan2.2_fun/README_TRAIN_CONTROL_LORA_zh-CN.md) |
|
||||
| CogVideoX-Fun | [EN](scripts/cogvideox_fun/README_TRAIN.md) / [ZH](scripts/cogvideox_fun/README_TRAIN_zh-CN.md) | [EN](scripts/cogvideox_fun/README_TRAIN_LORA.md) / [ZH](scripts/cogvideox_fun/README_TRAIN_LORA_zh-CN.md) | [Control ZH](scripts/cogvideox_fun/README_TRAIN_CONTROL_zh-CN.md)、[Reward LoRA](scripts/cogvideox_fun/README_TRAIN_REWARD.md) |
|
||||
| Qwen-Image | [EN](scripts/qwenimage/README_TRAIN.md) / [ZH](scripts/qwenimage/README_TRAIN_zh-CN.md) | [EN](scripts/qwenimage/README_TRAIN_LORA.md) / [ZH](scripts/qwenimage/README_TRAIN_LORA_zh-CN.md) | [Edit ZH](scripts/qwenimage/README_TRAIN_EDIT_zh-CN.md) |
|
||||
| Qwen-Image-2.1 | [EN](scripts/qwenimage21/README_TRAIN.md) / [ZH](scripts/qwenimage21/README_TRAIN_zh-CN.md) | - | - |
|
||||
| Z-Image | [EN](scripts/z_image/README_TRAIN.md) / [ZH](scripts/z_image/README_TRAIN_zh-CN.md) | [EN](scripts/z_image/README_TRAIN_LORA.md) / [ZH](scripts/z_image/README_TRAIN_LORA_zh-CN.md) | [GRPO LoRA](scripts/z_image/README_TRAIN_GRPO_LORA.md) |
|
||||
|
||||
その他のモデルも同様に、対応する`scripts/{model_name}/`下のREADMEを参照してください。
|
||||
|
||||
# 三、サポート済みモデル
|
||||
|
||||
下表は、現在サポートされているモデル系列と重みをまとめたものです。ビデオモデルと画像モデルは同じ推論・訓練インターフェースを共有しています。各行は1つのモデル系列を表し、第4列は4列のHTML埋め込みテーブル(重み、Hugging Face、ModelScope、説明)です。🤗 は Hugging Face、🤖 は ModelScope(中国国内ネットワーク向け)、`-` は該当チャネルに対応リポジトリがないか、ログイン認証が必要なことを示します。各モデルの訓練ドキュメントについては[3.3 各モデルの訓練ドキュメント](#33-各モデルの訓練ドキュメント)を参照してください。
|
||||
|
||||
| モデル系列 | モダリティ | サポートタスク | 重み / ダウンロード / 説明 |
|
||||
|--|--|--|--|
|
||||
| Wan2.2-Fun | ビデオ | 本プロジェクトがWan2.2で訓練した系列。テキスト/画像から動画、首尾画像、制御生成、カメラ制御をカバー | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-A14B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-Fun-14Bのテキスト・画像から動画を生成するモデルの重み。複数の解像度で学習されており、動画の最初と最後のフレームの予測をサポートしています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-A14B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-Fun-14Bの動画制御用重み。Canny、Depth、Pose、MLSDなどのさまざまな制御条件に対応しており、軌跡制御もサポートしています。512、768、1024の複数解像度での動画生成が可能で、81フレーム、16fpsで学習されています。多言語対応の予測もサポートしています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-A14B-Control-Camera</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control-Camera">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control-Camera">🤖</a></td><td valign="top" style="padding:2px 0;">14B Controlにカメラモーション制御を追加</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-5B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-Fun-5B テキストから動画生成用の重み。121フレーム、24 FPSで学習され、先頭/末尾フレーム予測をサポート。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-5B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-Fun-5B 動画制御用重み。Canny、Depth、Pose、MLSDなどの制御条件や軌道制御をサポート。121フレーム、24 FPSで学習され、多言語予測に対応。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-5B-Control-Camera</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control-Camera">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control-Camera">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-Fun-5B カメラレンズ制御用重み。121フレーム、24 FPSで学習され、多言語予測に対応。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-Reward-LoRAs</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-Reward-LoRAs">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-Reward-LoRAs">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-Fun生成動画を報酬逆伝播で最適化するReward LoRA集合</td></tr></table> |
|
||||
| Wan2.2-VACE-Fun | ビデオ | 本プロジェクトがVACE方式で訓練した系列。制御生成と主題参照をカバー | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-VACE-Fun-A14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-VACE-Fun-A14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-VACE-Fun-A14B">🤖</a></td><td valign="top" style="padding:2px 0;">VACE方式でトレーニングされたWan2.2の制御ウェイト(ベースモデルはWan2.2-T2V-A14B)。Canny、Depth、Pose、MLSD、軌道制御などの異なる制御条件をサポートします。対象を指定して動画生成が可能です。多解像度(512、768、1024)の動画予測をサポートし、81フレームで16FPSでトレーニングされています。多言語予測にも対応しています。</td></tr></table> |
|
||||
| Wan2.2 | ビデオ | Wan公式重み。テキスト/画像から動画、音声駆動、キャラクターアニメーションをカバー。Wan2.2-Fun系列の訓練基線としても使用可能 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-TI2V-5B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.2-TI2V-5B">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-5B テキスト/画像から動画生成重み</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-T2V-A14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-T2V-A14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.2-T2V-A14B">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-14B テキストから動画生成重み</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-I2V-A14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-I2V-A14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.2-I2V-A14B">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-14B 画像から動画生成重み</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-S2V-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-S2V-14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Wan-AI/Wan2.2-S2V-14B">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-14B 音声から動画生成重み、話者駆動デジタルヒューマン</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Animate-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-Animate-14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Wan-AI/Wan2.2-Animate-14B">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.2-14B キャラクター置換・モーション転移重み。リポジトリに複数精度ファイルを含む</td></tr></table> |
|
||||
| Wan2.1-Fun V1.1 | ビデオ | 本プロジェクトがWan2.1で訓練したV1.1系列。マルチ解像度(512/768/1024)、81フレーム16fps、テキスト/画像から動画、首尾画像、制御生成、カメラ制御をカバー | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-1.3B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-V1.1-1.3Bのテキスト・画像から動画生成の重み。マルチ解像度で訓練され、最初と最後の画像予測をサポートします。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-14B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-V1.1-14Bのテキスト・画像から動画生成の重み。マルチ解像度で訓練され、最初と最後の画像予測をサポートします。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-1.3B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-V1.1-1.3Bのビデオ制御重み。Canny、Depth、Pose、MLSDなどの異なる制御条件に対応し、参照画像+制御条件を使用した制御や軌跡制御をサポートします。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-14B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-V1.1-14Bのビデオ制御重み。Canny、Depth、Pose、MLSDなどの異なる制御条件に対応し、参照画像+制御条件を使用した制御や軌跡制御をサポートします。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-1.3B-Control-Camera</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control-Camera">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control-Camera">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-V1.1-1.3Bのカメラレンズ制御重み。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-14B-Control-Camera</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control-Camera">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control-Camera">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-V1.1-14Bのカメラレンズ制御重み。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。</td></tr></table> |
|
||||
| Wan2.1-Fun V1.0 | ビデオ | 本プロジェクトがWan2.1で訓練したV1.0系列。V1.1と同じ能力だがカメラ制御は非対応 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-1.3B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-1.3Bのテキスト・画像から動画生成する重み。マルチ解像度で学習され、開始・終了画像予測をサポート。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-14B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-14Bのテキスト・画像から動画生成する重み。マルチ解像度で学習され、開始・終了画像予測をサポート。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-1.3B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-1.3Bのビデオ制御ウェイト。Canny、Depth、Pose、MLSDなどの異なる制御条件をサポートし、トラジェクトリ制御も利用可能。512、768、1024のマルチ解像度でのビデオ予測をサポートし、81フレーム(1秒間に16フレーム)でトレーニング済みで、多言語予測にも対応しています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-14B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">Wan2.1-Fun-14Bのビデオ制御ウェイト。Canny、Depth、Pose、MLSDなどの異なる制御条件をサポートし、トラジェクトリ制御も利用可能。512、768、1024のマルチ解像度でのビデオ予測をサポートし、81フレーム(1秒間に16フレーム)でトレーニング済みで、多言語予測にも対応しています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-Reward-LoRAs</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-Reward-LoRAs">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-Reward-LoRAs">🤖</a></td><td valign="top" style="padding:2px 0;">報酬逆伝播で訓練された整列LoRA</td></tr></table> |
|
||||
| Wan2.1 | ビデオ | Wan公式重み。テキスト/画像から動画、音声駆動、制御生成をカバー。Wan2.1-Fun系列の訓練基線としても使用可能 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-T2V-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-1.3B">🤖</a></td><td valign="top" style="padding:2px 0;">1.3B文生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-T2V-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-T2V-14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-14B">🤖</a></td><td valign="top" style="padding:2px 0;">14B文生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-I2V-14B-480P</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-480P">🤖</a></td><td valign="top" style="padding:2px 0;">480P图生视频,是InfiniteTalk的基础模型</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-I2V-14B-720P</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P">🤖</a></td><td valign="top" style="padding:2px 0;">万象2.1-14B-720P 画像→動画モデルの重み</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-VACE-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-VACE-1.3B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Wan-AI/Wan2.1-VACE-1.3B">🤖</a></td><td valign="top" style="padding:2px 0;">1.3B VACE制御と主題参照</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-VACE-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-VACE-14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Wan-AI/Wan2.1-VACE-14B">🤖</a></td><td valign="top" style="padding:2px 0;">14B VACE制御と主題参照</td></tr></table> |
|
||||
| Self-Forcing / Causal-Forcing / Flex-Forcing | ビデオ | 自己回帰蒸留方案。ストリーミング生成、インタラクティブ生成、チャンク単位の注意をカバー | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Self-Forcing</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/gdhe17/Self-Forcing">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/AI-ModelScope/Self-Forcing">🤖</a></td><td valign="top" style="padding:2px 0;">自己回帰蒸留重み、Wan2.1-T2Vと組み合わせて流式・インタラクティブ生成に対応;Flex-Forcing(チャンク単位の因果/双方向注意)の重みは`scripts/wan2.1_flex_forcing`で訓練して生成</td></tr></table> |
|
||||
| TurboWan / TurboDiffusion | ビデオ | TurboDiffusion方案が公開した少ステップ蒸留重み | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">TurboWan2.1-T2V-1.3B-480P</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/TurboDiffusion/TurboWan2.1-T2V-1.3B-480P">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/TurboDiffusion/TurboWan2.1-T2V-1.3B-480P">🤖</a></td><td valign="top" style="padding:2px 0;">1.3Bテキストから動画生成の蒸留重み。公式は.pth形式で公開、リポジトリに量子化版も含む</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">TurboWan2.2-I2V-A14B-720P</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/TurboDiffusion/TurboWan2.2-I2V-A14B-720P">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/TurboDiffusion/TurboWan2.2-I2V-A14B-720P">🤖</a></td><td valign="top" style="padding:2px 0;">14B画像から動画生成の蒸留重み。リポジトリにlow/highの2種類のノイズモデル(量子化版も含む)を含み、Personalized_Modelに配置しpredictファイルのtransformer_path/transformer_high_pathで指定</td></tr></table> |
|
||||
| CogVideoX-Fun V1.5 | ビデオ | 公式CogVideoX-Fun V1.5重み。マルチ解像度(512/768/1024)、85フレーム8fps、画像から動画と報酬整列をカバー | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.5-5b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-5b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-5b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024)でビデオを予測できます。85フレーム、8フレーム/秒でトレーニングされています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.5-Reward-LoRAs</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-Reward-LoRAs">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs">🤖</a></td><td valign="top" style="padding:2px 0;">公式の報酬逆伝播技術モデルで、CogVideoX-Fun-V1.5が生成するビデオを最適化し、人間の嗜好によりよく合うようにする。</td></tr></table> |
|
||||
| CogVideoX-Fun V1.1 | ビデオ | 公式CogVideoX-Fun V1.1重み。マルチ解像度(512/768/1024/1280)、49フレーム8fps、画像から動画、ポーズ制御、制御生成、報酬整列をカバー | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-2b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。参照画像にノイズが追加され、V1.0と比較して動きの幅が広がっています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-5b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。参照画像にノイズが追加され、V1.0と比較して動きの幅が広がっています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-2b-Pose</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Pose">🤖</a></td><td valign="top" style="padding:2px 0;">公式のポーズコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-5b-Pose</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Pose">🤖</a></td><td valign="top" style="padding:2px 0;">公式のポーズコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-2b-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Control">🤖</a></td><td valign="top" style="padding:2px 0;">公式のコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。Canny、Depth、Pose、MLSDなどのさまざまなコントロール条件をサポートします。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-5b-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Control">🤖</a></td><td valign="top" style="padding:2px 0;">公式のコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。Canny、Depth、Pose、MLSDなどのさまざまなコントロール条件をサポートします。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-Reward-LoRAs</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-Reward-LoRAs">🤖</a></td><td valign="top" style="padding:2px 0;">公式の報酬逆伝播技術モデルで、CogVideoX-Fun-V1.1が生成するビデオを最適化し、人間の嗜好によりよく合うようにする。</td></tr></table> |
|
||||
| CogVideoX-Fun V1.0 | ビデオ | 旧版重み。49フレーム8fpsで訓練。V1.1/V1.5に置き換え済み | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-2b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-2b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-5b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-5b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。</td></tr></table> |
|
||||
| HunyuanVideo | ビデオ | 公式diffusers形式重み。本プロジェクトは推論とLoRA訓練を直接サポート | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">HunyuanVideo</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/hunyuanvideo-community/HunyuanVideo">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Tencent-Hunyuan/HunyuanVideo">🤖</a></td><td valign="top" style="padding:2px 0;">文生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">HunyuanVideo-I2V</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/hunyuanvideo-community/HunyuanVideo-I2V">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Tencent-Hunyuan/HunyuanVideo-I2V">🤖</a></td><td valign="top" style="padding:2px 0;">图生视频</td></tr></table> |
|
||||
| MiniMax-H3 | ビデオ | 公式動画生成重みと本プロジェクトが訓練したControlNet | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">MiniMax-H3</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/MiniMaxAI/MiniMax-H3">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/MiniMax/MiniMax-H3">🤖</a></td><td valign="top" style="padding:2px 0;">MiniMax-H3公式T2V/I2V重み</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">MiniMax-H3-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/MiniMax-H3-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/MiniMax-H3-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">本プロジェクトが訓練したControlNet。複数制御条件と軌跡制御をサポート</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">MiniMax-H3-Fun-Controlnet-Union-2.0</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/MiniMax-H3-Fun-Controlnet-Union-2.0">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/MiniMax-H3-Fun-Controlnet-Union-2.0">🤖</a></td><td valign="top" style="padding:2px 0;">本プロジェクトが訓練したControlNet(2.0版)。複数制御条件、軌跡制御、inpaint重みをサポート</td></tr></table> |
|
||||
| TaoMate-H3 | ビデオ+音声 | MiniMax-H3をベースにした公式ストリーミング音声・動画生成アダプタ | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">TaoMate-H3-Adapter</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/TaoLiveAIGC/TaoMate-H3">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/TaoLiveAIGC/TaoMate-H3">🤖</a></td><td valign="top" style="padding:2px 0;">公式rank 128アダプタ(step-3000 EMA)。3ステップ蒸留サンプリングスケジュールを内蔵し、ストリーミング音声駆動生成に対応;MiniMax-H3基盤重みと組み合わせて使用</td></tr></table> |
|
||||
| LTX-2 | ビデオ+音声 | 公式DiT音声・動画共同生成重み | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">LTX-2</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Lightricks/LTX-2">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Lightricks/LTX-2">🤖</a></td><td valign="top" style="padding:2px 0;">音声・動画共同生成の公式重み。リポジトリに複数精度ファイルを含む</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">LTX-2.3-Diffusers</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/dg845/LTX-2.3-Diffusers">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">v2.3はコミュニティ変換のdiffusers形式重みを使用。公式重みはLightricks/LTX-2.3を参照</td></tr></table> |
|
||||
| LongCat-Video | ビデオ | 公式長尺動画生成重み。LoRA訓練をサポート | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">LongCat-Video</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/meituan-longcat/LongCat-Video">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/meituan-longcat/LongCat-Video">🤖</a></td><td valign="top" style="padding:2px 0;">LongCat-Video公式T2V重み</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">LongCat-Video-Avatar</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/meituan-longcat/LongCat-Video-Avatar">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/meituan-longcat/LongCat-Video-Avatar">🤖</a></td><td valign="top" style="padding:2px 0;">LongCat-Video公式アバター/デジタルヒューマン重み</td></tr></table> |
|
||||
| FantasyTalking | 音声駆動ビデオ | 音声条件付き増分重み。基盤ビデオ重みと音声エンコーダが必要 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">FantasyTalking</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/acvlab/FantasyTalking">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/amap_cvlab/FantasyTalking">🤖</a></td><td valign="top" style="padding:2px 0;">需搭配Wan2.1-I2V-14B-720P使用</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">wav2vec2-base-960h</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/facebook/wav2vec2-base-960h">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/AI-ModelScope/wav2vec2-base-960h">🤖</a></td><td valign="top" style="padding:2px 0;">音频编码器,放入基础权重目录并命名为audio_encoder</td></tr></table> |
|
||||
| InfiniteTalk | 音声駆動ビデオ | 音声条件付き増分重み。基盤ビデオ重みと音声エンコーダが必要 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">InfiniteTalk</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/MeiGen-AI/InfiniteTalk">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/MeiGen-AI/InfiniteTalk">🤖</a></td><td valign="top" style="padding:2px 0;">InfiniteTalk公式オーディオ駆動重み</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">chinese-wav2vec2-base</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/TencentGameMate/chinese-wav2vec2-base">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/TencentGameMate/chinese-wav2vec2-base">🤖</a></td><td valign="top" style="padding:2px 0;">中国語音声エンコーダ</td></tr></table> |
|
||||
| FlashHead | 音声駆動ビデオ | 公式高品質頭部動作デジタルヒューマン重み | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">SoulX-FlashHead-1_3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Soul-AILab/SoulX-FlashHead-1_3B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Soul-AILab/SoulX-FlashHead-1_3B">🤖</a></td><td valign="top" style="padding:2px 0;">SoulX FlashHead 1.3B 音声駆動頭部重み。wav2vec音声エンコーダが必要</td></tr></table> |
|
||||
| MOVA | ビデオ+音声 | 公式MOVA重み | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">MOVA-360p</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/OpenMOSS-Team/MOVA-360p">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/OpenMOSS/MOVA-360p">🤖</a></td><td valign="top" style="padding:2px 0;">画像から動画と音声・動画共同生成</td></tr></table> |
|
||||
| LingBot | ビデオ | カメラ制御可能なワールドモデル。ディレクトリ構造はWan2.2-I2V-A14Bと一致 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-world-base-cam</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-world-base-cam">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-world-base-cam">🤖</a></td><td valign="top" style="padding:2px 0;">カメラ制御基線重み</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-video-rewriter-lora</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-video-rewriter-lora">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-video-rewriter-lora">🤖</a></td><td valign="top" style="padding:2px 0;">rewriter LoRA。Qwen3.6-27Bで構造化キャプションを生成して使用</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-video-dense-1.3b</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-video-dense-1.3b">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-video-dense-1.3b">🤖</a></td><td valign="top" style="padding:2px 0;">1.3B dense版動画生成重み。1〜2枚のGPUで訓練可能</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-video-moe-30b-a3b</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-video-moe-30b-a3b">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-video-moe-30b-a3b">🤖</a></td><td valign="top" style="padding:2px 0;">30B MoE(3Bアクティブ)動画生成重み。訓練には8×80GB以上を推奨</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-world-fast</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-world-fast">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-world-fast">🤖</a></td><td valign="top" style="padding:2px 0;">蒸留少ステップワールドモデル(transformerは16シャード)。VAE/T5はlingbot-world-base-camを再利用し、推論にはFlow_Unipcサンプラーを使用</td></tr></table> |
|
||||
| Phantom | ビデオ | 複数主体参照による動画生成の増分重み。Wan2.1-T2Vベース | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">1.3B版。公式は.pth形式で公開。Personalized_Modelに配置しpredictファイルのtransformer_pathで指定</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">14B版。公式は分割safetensors形式で公開</td></tr></table> |
|
||||
| Qwen-Image | 画像 | 公式テキストから画像生成・画像編集重み。基線とLoRA訓練をサポート | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image">🤖</a></td><td valign="top" style="padding:2px 0;">文生图基础权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2512">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2512">🤖</a></td><td valign="top" style="padding:2px 0;">テキストから画像生成の更新版</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit-2509</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit-2509">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑更新版本</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Layered</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Layered">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Layered">🤖</a></td><td valign="top" style="padding:2px 0;">画像レイヤー分解重み。画像を複数の編集可能なRGBAレイヤーに分解可能</td></tr></table> |
|
||||
| Qwen-Image-2.1 | 画像 | 公式次世代テキストから画像生成重み。シングルストリームblock-causal構造、プレフィックスKV cacheに対応 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">シングルストリームblock-causal構造。全パラメータ訓練をサポート、プレフィックスKV cacheで推論を高速化</td></tr></table> |
|
||||
| Qwen-Image ControlNet | 画像 | 画像制御生成。Canny、Depth、Pose、MLSD、Scribbleをサポート | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">Qwen-Image-2512のControlNet重み。Canny、Depth、Pose、MLSD、Scribbleなど、複数の制御条件をサポートします。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">InstantX提供の同種ControlNet</td></tr></table> |
|
||||
| Z-Image | 画像 | 公式テキストから画像生成重み | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image">🤖</a></td><td valign="top" style="padding:2px 0;">基础版</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image-Turbo">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo">🤖</a></td><td valign="top" style="padding:2px 0;">加速版</td></tr></table> |
|
||||
| Z-Image-Fun | 画像 | 本プロジェクトがZ-Imageで訓練したControlNetと蒸留LoRA。Canny、Depth、Pose、MLSD、Scribble、Grayをサポート | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">Z-ImageのControlNet重み、Canny、Depth、Pose、MLSD、ScribbleおよびGrayなど複数の制御条件に対応。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">Z-Image-Turbo用のControlNet重み。Canny、Depth、Pose、MLSDなど複数の制御条件をサポート。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">Z-Image-TurboのControlNet重み。第1版と比較して、より多くの層に追加され、より長時間トレーニングされています。Canny、Depth、Pose、MLSDなど、複数の制御条件をサポートしています。</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Lora-Distill</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill">🤖</a></td><td valign="top" style="padding:2px 0;">これはZ-Image用の蒸留LoRAで、ステップ数とCFGの両方を蒸留します。このモデルはCFGを必要とせず、推論には8ステップを使用します。</td></tr></table> |
|
||||
| Flux | 画像 | 公式FLUX.1/FLUX.2重みと本プロジェクトが訓練したControlNet | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.1-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.1-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev">🤖</a></td><td valign="top" style="padding:2px 0;">文生图与图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.2-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev">🤖</a></td><td valign="top" style="padding:2px 0;">第二代官方权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">FLUX.2-dev用ControlNet重み</td></tr></table> |
|
||||
| ERNIE-Image | 画像 | Baidu公式テキストから画像生成重み | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">ERNIE-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/baidu/ERNIE-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PaddlePaddle/ERNIE-Image">🤖</a></td><td valign="top" style="padding:2px 0;">ERNIE-Image公式画像生成重み</td></tr></table> |
|
||||
| Lens | 画像 | Microsoft公式カメラ制御重み | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Lens</td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/microsoft/Lens">🤖</a></td><td valign="top" style="padding:2px 0;">Lens公式カメラ制御重み</td></tr></table> |
|
||||
| 補助モデル | - | 生成モデルではなく、報酬整列、データアノテーション、高速デコードに使用 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">HPSv3</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/MizzenAI/HPSv3">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/MizzenAI/HPSv3">🤖</a></td><td valign="top" style="padding:2px 0;">報酬逆伝播で使用されるスコアリングモデル</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen2-VL-7B-Instruct</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen2-VL-7B-Instruct">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen2-VL-7B-Instruct">🤖</a></td><td valign="top" style="padding:2px 0;">動画キャプション生成パイプラインで使用されるマルチモーダルエンコーダ</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">taew2_1 / taew2_2</td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">Tiny AutoEncoder(約20MB)。Wan2.1/Wan2.2 VAEと同じlatent空間を共有し、デコード速度は完全なVAEの約100倍で、高速プレビューや低メモリ生成に使用;重みは<a href="https://github.com/madebyollin/taehv">madebyollin/taehv</a>より</td></tr></table> |
|
||||
|
||||
> 補足説明:
|
||||
> - 音声駆動・参照系モデル(FantasyTalking、InfiniteTalk、Phantom、TaoMate-H3)は増分重みであり、対応する基盤ビデオ重みと音声エンコーダを同時にダウンロードする必要があります。
|
||||
> - TurboDiffusion方案はTurboWan系列の蒸留重みを公開済みです(上表参照)。Flex-Forcing、PDDなどその他の蒸留方案は公開重みがなく、`scripts/{model_name}/README_TRAIN*.md`で訓練後、`transformer_path`に指定して使用できます。
|
||||
> - 重み名は`models/Diffusion_Transformer/`下のフォルダ名と一対一で対応します。同じ系列内の各重みは互換性がないため、推論タスクに応じて選択してください。ここに掲載されていない重みは、本プロジェクトの訓練成果物、または上流の公式リポジトリから取得する必要があります。
|
||||
|
||||
# 四、ビデオ作品
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-InP && Wan2.1-Fun-V1.1-1.3B-InP
|
||||
|
||||
@@ -178,14 +408,15 @@ Linuxの詳細:
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
|
||||
|
||||
Generic Control Video + Reference Image:
|
||||
汎用制御動画 + 参照画像:
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Reference Image
|
||||
参照画像
|
||||
</td>
|
||||
<td>
|
||||
Control Video
|
||||
制御動画
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-14B-Control
|
||||
@@ -193,6 +424,7 @@ Generic Control Video + Reference Image:
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-1.3B-Control
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
@@ -206,11 +438,12 @@ Generic Control Video + Reference Image:
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
汎用制御動画(Canny、Pose、Depth など)と軌跡制御:
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
@@ -222,7 +455,7 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
@@ -236,6 +469,7 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
@@ -262,6 +496,7 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<td>
|
||||
Pan Right
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload loop></video>
|
||||
@@ -272,6 +507,7 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
Pan Down
|
||||
@@ -282,6 +518,7 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<td>
|
||||
Pan Up + Pan Right
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload loop></video>
|
||||
@@ -368,6 +605,7 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
美しい澄んだ目と金髪の若い女性が白い服を着て体をひねり、カメラは彼女の顔に焦点を合わせています。高品質、傑作、最高品質、高解像度、超微細、夢のような。
|
||||
@@ -392,299 +630,7 @@ Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
# 使い方
|
||||
|
||||
<h3 id="video-gen">1. 生成</h3>
|
||||
|
||||
#### a. GPUメモリ節約方法
|
||||
Wan2.1のパラメータが非常に大きいため、GPUメモリを節約し、コンシューマー向けGPUに適応させる必要があります。各予測ファイルには`GPU_memory_mode`を提供しており、`model_cpu_offload`、`model_cpu_offload_and_qfloat8`、`sequential_cpu_offload`の中から選択できます。この方法はCogVideoX-Funの生成にも適用されます。
|
||||
|
||||
- `model_cpu_offload`: モデル全体が使用後にCPUに移動し、一部のGPUメモリを節約します。
|
||||
- `model_cpu_offload_and_qfloat8`: モデル全体が使用後にCPUに移動し、Transformerモデルに対してfloat8の量子化を行い、より多くのGPUメモリを節約します。
|
||||
- `sequential_cpu_offload`: モデルの各層が使用後にCPUに移動します。速度は遅くなりますが、大量のGPUメモリを節約します。
|
||||
|
||||
`qfloat8`はモデルの性能を部分的に低下させる可能性がありますが、より多くのGPUメモリを節約できます。十分なGPUメモリがある場合は、`model_cpu_offload`の使用をお勧めします。
|
||||
|
||||
#### b. ComfyUIを使用する
|
||||
詳細は[ComfyUI README](comfyui/README.md)をご覧ください。
|
||||
|
||||
#### c. Pythonファイルを実行する
|
||||
|
||||
##### i. 単一GPUでの推論:
|
||||
|
||||
- ステップ1: 対応する[重み](#model-zoo)をダウンロードし、`models`フォルダに配置します。
|
||||
- ステップ2: 異なる重みと予測目標に基づいて、異なるファイルを使用して予測を行います。現在、このライブラリはCogVideoX-Fun、Wan2.1、およびWan2.1-Funをサポートしています。`examples`フォルダ内のフォルダ名で区別され、異なるモデルがサポートする機能が異なりますので、状況に応じて区別してください。以下はCogVideoX-Funを例として説明します。
|
||||
- テキストからビデオ:
|
||||
- `examples/cogvideox_fun/predict_t2v.py`ファイルで`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- 次に、`examples/cogvideox_fun/predict_t2v.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos`フォルダに保存されます。
|
||||
- 画像からビデオ:
|
||||
- `examples/cogvideox_fun/predict_i2v.py`ファイルで`validation_image_start`、`validation_image_end`、`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- `validation_image_start`はビデオの開始画像、`validation_image_end`はビデオの終了画像です。
|
||||
- 次に、`examples/cogvideox_fun/predict_i2v.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos_i2v`フォルダに保存されます。
|
||||
- ビデオからビデオ:
|
||||
- `examples/cogvideox_fun/predict_v2v.py`ファイルで`validation_video`、`validation_image_end`、`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- `validation_video`はビデオ生成のための参照ビデオです。以下のデモビデオを使用して実行できます:[デモビデオ](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/play_guitar.mp4)
|
||||
- 次に、`examples/cogvideox_fun/predict_v2v.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos_v2v`フォルダに保存されます。
|
||||
- 通常の制御付きビデオ生成(Canny、Pose、Depthなど):
|
||||
- `examples/cogvideox_fun/predict_v2v_control.py`ファイルで`control_video`、`validation_image_end`、`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- `control_video`は、Canny、Pose、Depthなどの演算子で抽出された制御用ビデオです。以下のデモビデオを使用して実行できます:[デモビデオ](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/pose.mp4)
|
||||
- 次に、`examples/cogvideox_fun/predict_v2v_control.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos_v2v_control`フォルダに保存されます。
|
||||
- ステップ3: 自分でトレーニングした他のバックボーンやLoraを組み合わせたい場合は、必要に応じて`examples/{model_name}/predict_t2v.py`や`examples/{model_name}/predict_i2v.py`、`lora_path`を修正します。
|
||||
|
||||
##### ii. 複数GPUでの推論:
|
||||
多カードでの推論を行う際は、xfuserリポジトリのインストールに注意してください。xfuser==0.4.2 と yunchang==0.6.2 のインストールが推奨されます。
|
||||
```
|
||||
pip install xfuser==0.4.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
pip install yunchang==0.6.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
```
|
||||
|
||||
`ulysses_degree` と `ring_degree` の積が使用する GPU 数と一致することを確認してください。たとえば、8つのGPUを使用する場合、`ulysses_degree=2` と `ring_degree=4`、または `ulysses_degree=4` と `ring_degree=2` を設定することができます。
|
||||
|
||||
- `ulysses_degree` はヘッド(head)に分割した後の並列化を行います。
|
||||
- `ring_degree` はシーケンスに分割した後の並列化を行います。
|
||||
|
||||
`ring_degree` は `ulysses_degree` よりも通信コストが高いため、これらのパラメータを設定する際には、シーケンス長とモデルのヘッド数を考慮する必要があります。
|
||||
|
||||
8GPUでの並列推論を例に挙げます:
|
||||
|
||||
- **Wan2.1-Fun-V1.1-14B-InP** はヘッド数が40あります。この場合、`ulysses_degree` は40で割り切れる値(例:2, 4, 8など)に設定する必要があります。したがって、8GPUを使用して並列推論を行う場合、`ulysses_degree=8` と `ring_degree=1` を設定できます。
|
||||
|
||||
- **Wan2.1-Fun-V1.1-1.3B-InP** はヘッド数が12あります。この場合、`ulysses_degree` は12で割り切れる値(例:2, 4など)に設定する必要があります。したがって、8GPUを使用して並列推論を行う場合、`ulysses_degree=4` と `ring_degree=2` を設定できます。
|
||||
|
||||
パラメータの設定が完了したら、以下のコマンドで並列推論を実行してください:
|
||||
|
||||
```sh
|
||||
torchrun --nproc-per-node=8 examples/wan2.1_fun/predict_t2v.py
|
||||
```
|
||||
|
||||
#### d. UIインターフェースを使用する
|
||||
|
||||
WebUIは、テキストからビデオ、画像からビデオ、ビデオからビデオ、および通常の制御付きビデオ生成(Canny、Pose、Depthなど)をサポートします。現在、このライブラリはCogVideoX-Fun、Wan2.1、およびWan2.1-Funをサポートしており、`examples`フォルダ内のフォルダ名で区別されています。異なるモデルがサポートする機能が異なるため、状況に応じて区別してください。以下はCogVideoX-Funを例として説明します。
|
||||
|
||||
- ステップ1: 対応する[重み](#model-zoo)をダウンロードし、`models`フォルダに配置します。
|
||||
- ステップ2: `examples/cogvideox_fun/app.py`ファイルを実行し、Gradioページに入ります。
|
||||
- ステップ3: ページ上で生成モデルを選択し、`prompt`、`neg_prompt`、`guidance_scale`、`seed`などを入力し、「生成」をクリックして結果が生成されるのを待ちます。結果は`sample`フォルダに保存されます。
|
||||
|
||||
### 2. モデルのトレーニング
|
||||
完全なモデルトレーニングの流れには、データの前処理とVideo DiTのトレーニングが含まれるべきです。異なるモデルのトレーニングプロセスは類似しており、データ形式も類似しています:
|
||||
|
||||
<h4 id="data-preprocess">a. データ前処理</h4>
|
||||
|
||||
画像データを使用してLoraモデルをトレーニングする簡単なデモを提供しました。詳細は[wiki](https://github.com/aigc-apps/CogVideoX-Fun/wiki/Training-Lora)をご覧ください。
|
||||
|
||||
長いビデオのセグメンテーション、クリーニング、説明のための完全なデータ前処理リンクは、ビデオキャプションセクションの[README](cogvideox/video_caption/README.md)を参照してください。
|
||||
|
||||
テキストから画像およびビデオ生成モデルをトレーニングしたい場合。この形式でデータセットを配置する必要があります。
|
||||
|
||||
```
|
||||
📦 project/
|
||||
├── 📂 datasets/
|
||||
│ ├── 📂 internal_datasets/
|
||||
│ ├── 📂 train/
|
||||
│ │ ├── 📄 00000001.mp4
|
||||
│ │ ├── 📄 00000002.jpg
|
||||
│ │ └── 📄 .....
|
||||
│ └── 📄 json_of_internal_datasets.json
|
||||
```
|
||||
|
||||
json_of_internal_datasets.jsonは標準のJSONファイルです。json内のfile_pathは相対パスとして設定できます。以下のように:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "train/00000001.mp4",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "video"
|
||||
},
|
||||
{
|
||||
"file_path": "train/00000002.jpg",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "image"
|
||||
},
|
||||
.....
|
||||
]
|
||||
```
|
||||
|
||||
次のように絶対パスとして設定することもできます:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "/mnt/data/videos/00000001.mp4",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "video"
|
||||
},
|
||||
{
|
||||
"file_path": "/mnt/data/train/00000001.jpg",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "image"
|
||||
},
|
||||
.....
|
||||
]
|
||||
```
|
||||
|
||||
<h4 id="dit-train">b. Video DiTトレーニング </h4>
|
||||
|
||||
データ前処理時にデータ形式が相対パスの場合、```scripts/{model_name}/train.sh```を次のように設定します。
|
||||
```
|
||||
export DATASET_NAME="datasets/internal_datasets/"
|
||||
export DATASET_META_NAME="datasets/internal_datasets/json_of_internal_datasets.json"
|
||||
```
|
||||
|
||||
データ形式が絶対パスの場合、```scripts/train.sh```を次のように設定します。
|
||||
```
|
||||
export DATASET_NAME=""
|
||||
export DATASET_META_NAME="/mnt/data/json_of_internal_datasets.json"
|
||||
```
|
||||
|
||||
次に、scripts/train.shを実行します。
|
||||
```sh
|
||||
sh scripts/train.sh
|
||||
```
|
||||
いくつかのパラメータ設定の詳細について:
|
||||
Wan2.1-Funは[Readme Train](scripts/wan2.1_fun/README_TRAIN.md)と[Readme Lora](scripts/wan2.1_fun/README_TRAIN_LORA.md)を参照してください。
|
||||
Wan2.1は[Readme Train](scripts/wan2.1/README_TRAIN.md)と[Readme Lora](scripts/wan2.1/README_TRAIN_LORA.md)を参照してください。
|
||||
CogVideoX-Funは[Readme Train](scripts/cogvideox_fun/README_TRAIN.md)と[Readme Lora](scripts/cogvideox_fun/README_TRAIN_LORA.md)を参照してください。
|
||||
|
||||
# モデルの場所
|
||||
|
||||
## 1. Wan2.2-Fun
|
||||
|
||||
| 名前 | ストレージ容量 | Hugging Face | Model Scope | 説明 |
|
||||
|------|----------------|------------|-------------|------|
|
||||
| Wan2.2-Fun-A14B-InP | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-InP) | Wan2.2-Fun-14Bのテキスト・画像から動画を生成するモデルの重み。複数の解像度で学習されており、動画の最初と最後のフレームの予測をサポートしています。 |
|
||||
| Wan2.2-Fun-A14B-Control | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control) | Wan2.2-Fun-14Bの動画制御用重み。Canny、Depth、Pose、MLSDなどのさまざまな制御条件に対応しており、軌跡制御もサポートしています。512、768、1024の複数解像度での動画生成が可能で、81フレーム、16fpsで学習されています。多言語対応の予測もサポートしています。 |
|
||||
| Wan2.2-Fun-A14B-Contro-Camera | 64.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control-Camera) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control-Camera)| Wan2.2-Fun-14Bのカメラレンズ制御重み。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
| Wan2.2-VACE-Fun-A14B | 64.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.2-VACE-Fun-A14B) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.2-VACE-Fun-A14B) | VACE方式でトレーニングされたWan2.2の制御ウェイト(ベースモデルはWan2.2-T2V-A14B)。Canny、Depth、Pose、MLSD、軌道制御などの異なる制御条件をサポートします。対象を指定して動画生成が可能です。多解像度(512、768、1024)の動画予測をサポートし、81フレームで16FPSでトレーニングされています。多言語予測にも対応しています。 |
|
||||
| Wan2.2-Fun-5B-InP | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-InP) | Wan2.2-Fun-5B テキストから動画生成用の重み。121フレーム、24 FPSで学習され、先頭/末尾フレーム予測をサポート。 |
|
||||
| Wan2.2-Fun-5B-Control | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control)| Wan2.2-Fun-5B 動画制御用重み。Canny、Depth、Pose、MLSDなどの制御条件や軌道制御をサポート。121フレーム、24 FPSで学習され、多言語予測に対応。 |
|
||||
| Wan2.2-Fun-5B-Control-Camera | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control-Camera)| Wan2.2-Fun-5B カメラレンズ制御用重み。121フレーム、24 FPSで学習され、多言語予測に対応。 |
|
||||
|
||||
## 2. Wan2.2
|
||||
|
||||
| モデル名 | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|
|
||||
| Wan2.2-TI2V-5B | [🤗リンク](https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B) | [😄リンク](https://www.modelscope.cn/models/Wan-AI/Wan2.2-TI2V-5B) | 万象2.2-5B テキストから動画生成重み |
|
||||
| Wan2.2-T2V-A14B | [🤗リンク](https://huggingface.co/Wan-AI/Wan2.2-T2V-A14B) | [😄リンク](https://www.modelscope.cn/models/Wan-AI/Wan2.2-T2V-A14B) | 万象2.2-14B テキストから動画生成重み |
|
||||
| Wan2.2-I2V-A14B | [🤗リンク](https://huggingface.co/Wan-AI/Wan2.2-I2V-A14B) | [😄リンク](https://www.modelscope.cn/models/Wan-AI/Wan2.2-I2V-A14B) | 万象2.2-14B 画像から動画生成重み |
|
||||
|
||||
## 3. Wan2.1-Fun
|
||||
|
||||
V1.1:
|
||||
| 名称 | ストレージ容量 | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-V1.1-1.3B-InP | 19.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP) | Wan2.1-Fun-V1.1-1.3Bのテキスト・画像から動画生成の重み。マルチ解像度で訓練され、最初と最後の画像予測をサポートします。 |
|
||||
| Wan2.1-Fun-V1.1-14B-InP | 47.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP) | Wan2.1-Fun-V1.1-14Bのテキスト・画像から動画生成の重み。マルチ解像度で訓練され、最初と最後の画像予測をサポートします。 |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control | 19.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control)| Wan2.1-Fun-V1.1-1.3Bのビデオ制御重み。Canny、Depth、Pose、MLSDなどの異なる制御条件に対応し、参照画像+制御条件を使用した制御や軌跡制御をサポートします。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control)| Wan2.1-Fun-V1.1-14Bのビデオ制御重み。Canny、Depth、Pose、MLSDなどの異なる制御条件に対応し、参照画像+制御条件を使用した制御や軌跡制御をサポートします。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control-Camera | 19.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control-Camera) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control-Camera)| Wan2.1-Fun-V1.1-1.3Bのカメラレンズ制御重み。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
| Wan2.1-Fun-V1.1-14B-Control-Camera | 47.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control-Camera) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control-Camera)| Wan2.1-Fun-V1.1-14Bのカメラレンズ制御重み。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
|
||||
|
||||
V1.0:
|
||||
| 名称 | ストレージ容量 | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-InP) | Wan2.1-Fun-1.3Bのテキスト・画像から動画生成する重み。マルチ解像度で学習され、開始・終了画像予測をサポート。 |
|
||||
| Wan2.1-Fun-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP) | Wan2.1-Fun-14Bのテキスト・画像から動画生成する重み。マルチ解像度で学習され、開始・終了画像予測をサポート。 |
|
||||
| Wan2.1-Fun-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-Control) | Wan2.1-Fun-1.3Bのビデオ制御ウェイト。Canny、Depth、Pose、MLSDなどの異なる制御条件をサポートし、トラジェクトリ制御も利用可能。512、768、1024のマルチ解像度でのビデオ予測をサポートし、81フレーム(1秒間に16フレーム)でトレーニング済みで、多言語予測にも対応しています。 |
|
||||
| Wan2.1-Fun-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-Control) | Wan2.1-Fun-14Bのビデオ制御ウェイト。Canny、Depth、Pose、MLSDなどの異なる制御条件をサポートし、トラジェクトリ制御も利用可能。512、768、1024のマルチ解像度でのビデオ予測をサポートし、81フレーム(1秒間に16フレーム)でトレーニング済みで、多言語予測にも対応しています。 |
|
||||
|
||||
## 4. Wan2.1
|
||||
|
||||
| 名称 | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|
|
||||
| Wan2.1-T2V-1.3B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-1.3B) | 万象2.1-1.3Bのテキストから動画生成する重み |
|
||||
| Wan2.1-T2V-14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-14B) | 万象2.1-14Bのテキストから動画生成する重み |
|
||||
| Wan2.1-I2V-14B-480P | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-480P) | 万象2.1-14B-480Pの画像から動画生成する重み |
|
||||
| Wan2.1-I2V-14B-720P| [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | 万象2.1-14B-720Pの画像から動画生成する重み |
|
||||
|
||||
## 5. FantasyTalking
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-I2V-14B-720P | - | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | 万象2.1-14B-720P 画像→動画モデルの重み |
|
||||
| Wav2Vec | - | [🤗Link](https://huggingface.co/facebook/wav2vec2-base-960h) | [😄Link](https://modelscope.cn/models/AI-ModelScope/wav2vec2-base-960h) | Wav2Vecモデル。Wan2.1-I2V-14B-720Pフォルダ内に配置し、`audio_encoder` という名前に変更してください |
|
||||
| FantasyTalking model | - | [🤗Link](https://huggingface.co/acvlab/FantasyTalking/) | [😄Link](https://www.modelscope.cn/models/amap_cvlab/FantasyTalking/) | 公式Audio Condition重み |
|
||||
|
||||
## 6. Qwen-Image
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image | [🤗Link](https://huggingface.co/Qwen/Qwen-Image) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image) | Qwen-Image 公式重み |
|
||||
| Qwen-Image-Edit | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit) | Qwen-Image-Edit 公式重み |
|
||||
| Qwen-Image-Edit-2509 | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit-2509) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509) | Qwen-Image-Edit-2509 公式重み |
|
||||
|
||||
## 7. Qwen-Image-Fun
|
||||
|
||||
| 名前 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image-2512-Fun-Controlnet-Union | - | [🤗リンク](https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union) | [😄リンク](https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union) | Qwen-Image-2512のControlNet重み。Canny、Depth、Pose、MLSD、Scribbleなど、複数の制御条件をサポートします。 |
|
||||
|
||||
## 8. Z-Image
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image | [🤗リンク](https://huggingface.co/Tongyi-MAI/Z-Image) | [😄リンク](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image) | Z-Imageの公式重み |
|
||||
| Z-Image-Turbo | [🤗リンク](https://huggingface.co/Tongyi-MAI/Z-Image-Turbo) | [😄リンク](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo) | Z-Image-Turboの公式重み |
|
||||
|
||||
## 9. Z-Image-Fun
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image-Fun-Controlnet-Union-2.1 | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1) | Z-ImageのControlNet重み、Canny、Depth、Pose、MLSD、ScribbleおよびGrayなど複数の制御条件に対応。 |
|
||||
| Z-Image-Fun-Lora-Distill | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill) | これはZ-Image用の蒸留LoRAで、ステップ数とCFGの両方を蒸留します。このモデルはCFGを必要とせず、推論には8ステップを使用します。 |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union | - | [🤗リンク](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union) | [😄リンク](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union) | Z-Image-Turbo用のControlNet重み。Canny、Depth、Pose、MLSDなど複数の制御条件をサポート。 |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union-2.1 | - | [🤗リンク](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | [😄リンク](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | Z-Image-TurboのControlNet重み。第1版と比較して、より多くの層に追加され、より長時間トレーニングされています。Canny、Depth、Pose、MLSDなど、複数の制御条件をサポートしています。 |
|
||||
|
||||
## 10. Flux
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| FLUX.1-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.1-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev)| FLUX.1-dev 公式重み |
|
||||
| FLUX.2-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.2-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev) | FLUX.2-dev 公式重み |
|
||||
|
||||
## 11. Flux-Fun
|
||||
|
||||
| 名前 | ストレージ | Hugging Face | ModelScope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Flux.2-dev-Fun-Controlnet-Union | - | [🤗リンク](https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union) | [😄リンク](https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union) | Flux.2-dev 用の ControlNet 重みで、Canny、Depth、Pose、MLSD など様々な制御条件をサポートします。 |
|
||||
|
||||
## 12. HunyuanVideo
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| HunyuanVideo | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo) | - | HunyuanVideo-diffusers 公式重み |
|
||||
| HunyuanVideo-I2V | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo-I2V) | - | HunyuanVideo-I2V-diffusers 公式重み |
|
||||
|
||||
## 13. CogVideoX-Fun
|
||||
|
||||
V1.5:
|
||||
|
||||
| 名称 | ストレージスペース | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.5-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-5b-InP) | 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024)でビデオを予測できます。85フレーム、8フレーム/秒でトレーニングされています。 |
|
||||
| CogVideoX-Fun-V1.5-Reward-LoRAs | - | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs) | 公式の報酬逆伝播技術モデルで、CogVideoX-Fun-V1.5が生成するビデオを最適化し、人間の嗜好によりよく合うようにする。 |
|
||||
|
||||
V1.1:
|
||||
|
||||
| 名称 | ストレージスペース | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.1-2b-InP | 13.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-InP) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-InP) | 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。参照画像にノイズが追加され、V1.0と比較して動きの幅が広がっています。 |
|
||||
| CogVideoX-Fun-V1.1-5b-InP | 20.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP) | 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。参照画像にノイズが追加され、V1.0と比較して動きの幅が広がっています。 |
|
||||
| CogVideoX-Fun-V1.1-2b-Pose | 13.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Pose) | 公式のポーズコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。|
|
||||
| CogVideoX-Fun-V1.1-2b-Control | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Control) | 公式のコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。Canny、Depth、Pose、MLSDなどのさまざまなコントロール条件をサポートします。|
|
||||
| CogVideoX-Fun-V1.1-5b-Pose | 20.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Pose) | 公式のポーズコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。|
|
||||
| CogVideoX-Fun-V1.1-5b-Control | 20.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Control) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Control) | 公式のコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。Canny、Depth、Pose、MLSDなどのさまざまなコントロール条件をサポートします。|
|
||||
| CogVideoX-Fun-V1.1-Reward-LoRAs | - | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs) | 公式の報酬逆伝播技術モデルで、CogVideoX-Fun-V1.1が生成するビデオを最適化し、人間の嗜好によりよく合うようにする。 |
|
||||
|
||||
<details>
|
||||
<summary>(Obsolete) V1.0:</summary>
|
||||
|
||||
| 名称 | ストレージスペース | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP | 13.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-2b-InP) | 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。 |
|
||||
| CogVideoX-Fun-5b-InP | 20.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP)| [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-5b-InP)| 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。|
|
||||
</details>
|
||||
|
||||
# 参考文献
|
||||
# 五、参考文献
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
|
||||
- Wan2.1: https://github.com/Wan-Video/Wan2.1/
|
||||
@@ -700,7 +646,7 @@ V1.1:
|
||||
- ComfyUI-CameraCtrl-Wrapper: https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper
|
||||
- CameraCtrl: https://github.com/hehao13/CameraCtrl
|
||||
|
||||
# 引用
|
||||
# 六、引用
|
||||
|
||||
研究やプロジェクトでVideoX-Funを使用する場合は、以下の形式で引用してください:
|
||||
|
||||
@@ -714,7 +660,7 @@ V1.1:
|
||||
}
|
||||
```
|
||||
|
||||
# 制限とリスク
|
||||
# 七、制限とリスク
|
||||
|
||||
- 生成された動画には、特に複雑なシーンでアーティファクトや品質の問題がある場合があります。
|
||||
- モデルは、細かい詳細、テキストのレンダリング、または特定の芸術スタイルで苦労する場合があります。
|
||||
@@ -725,7 +671,7 @@ V1.1:
|
||||
|
||||
責任ある使用を推奨し、本番環境でのセーフガードの実装をお勧めします。
|
||||
|
||||
# ライセンス
|
||||
# 八、ライセンス
|
||||
このプロジェクトは[Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE)の下でライセンスされています。
|
||||
|
||||
CogVideoX-2Bモデル(対応するTransformersモジュール、VAEモジュールを含む)は、[Apache 2.0ライセンス](LICENSE)の下でリリースされています。
|
||||
|
||||
+307
-508
@@ -11,84 +11,37 @@ Wan-Fun:
|
||||
[English](./README.md) | 简体中文 | [日本語](./README_ja-JP.md)
|
||||
|
||||
# 目录
|
||||
- [简介](#简介)
|
||||
- [快速启动](#快速启动)
|
||||
- [视频作品](#视频作品)
|
||||
- [如何使用](#如何使用)
|
||||
- [模型地址](#模型地址)
|
||||
- [参考文献](#参考文献)
|
||||
- [引用](#引用)
|
||||
- [限制与风险](#限制与风险)
|
||||
- [许可证](#许可证)
|
||||
- [一、简介](#一简介)
|
||||
- [二、快速开始与使用](#二快速开始与使用)
|
||||
- [1. 环境准备](#1-环境准备)
|
||||
- [2. 推理生成](#2-推理生成)
|
||||
- [3. 模型训练](#3-模型训练)
|
||||
- [三、已支持的模型](#三已支持的模型)
|
||||
- [四、视频作品](#四视频作品)
|
||||
- [五、参考文献](#五参考文献)
|
||||
- [六、引用](#六引用)
|
||||
- [七、限制与风险](#七限制与风险)
|
||||
- [八、许可证](#八许可证)
|
||||
|
||||
# 简介
|
||||
VideoX-Fun是一个视频生成的pipeline,可用于生成AI图片与视频、训练Diffusion Transformer的基线模型与Lora模型,我们支持从已经训练好的基线模型直接进行预测,生成不同分辨率,不同秒数、不同FPS的视频,也支持用户训练自己的基线模型与Lora模型,进行一定的风格变换。
|
||||
# 一、简介
|
||||
VideoX-Fun是一个图片与视频生成的pipeline,可用于生成AI图片与视频、训练Diffusion Transformer的基线模型与Lora模型。我们同时支持视频与图片两类Diffusion Transformer模型:视频侧涵盖Wan2.1/Wan2.2(含Fun、VACE、Animate、S2V等变体)、CogVideoX-Fun、HunyuanVideo、MiniMax-H3、LTX-2、LongCat-Video、FantasyTalking与LingBot等,图片侧涵盖Qwen-Image(含Edit)、Z-Image(含Turbo)、Flux/Flux2与ERNIE-Image等,完整列表见[已支持的模型](#三已支持的模型)。在此基础上,我们支持从已经训练好的基线模型直接进行预测,生成不同分辨率、不同秒数、不同FPS的视频与不同分辨率的图片,也支持用户训练自己的基线模型与Lora模型,进行一定的风格变换。
|
||||
|
||||
我们会逐渐支持从不同平台快速启动,请参阅 [快速启动](#快速启动)。
|
||||
|
||||
新特性:
|
||||
- 更新支持Wan2.2系列模型、Wan-VACE控制模型、支持Fantasy Talking数字人模型、Qwen-Image和Flux图片生成模型等。[2025.10.16]。
|
||||
- 更新Wan2.1-Fun-V1.1版本:支持14B与1.3B模型Control+参考图模型,支持镜头控制,另外Inpaint模型重新训练,性能更佳。[2025.04.25]
|
||||
- 更新Wan2.1-Fun-V1.0版本:支持14B与1.3B模型的I2V和Control模型,支持首尾图预测。[2025.03.26]
|
||||
- 更新CogVideoX-Fun-V1.5版本:上传I2V模型与相关训练预测代码。[2024.12.16]
|
||||
- 奖励Lora支持:通过奖励反向传播技术训练Lora,以优化生成的视频,使其更好地与人类偏好保持一致,[更多信息](scripts/README_TRAIN_REWARD.md)。新版本的控制模型,支持不同的控制条件,如Canny、Depth、Pose、MLSD等。[2024.11.21]
|
||||
- diffusers支持:CogVideoX-Fun Control现在在diffusers中得到了支持。感谢 [a-r-r-o-w](https://github.com/a-r-r-o-w)在这个 [PR](https://github.com/huggingface/diffusers/pull/9671)中贡献了支持。查看[文档](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cogvideox)以了解更多信息。[2024.10.16]
|
||||
- 更新CogVideoX-Fun-V1.1版本:重新训练i2v模型,添加Noise,使得视频的运动幅度更大。上传控制模型训练代码与Control模型。[2024.09.29]
|
||||
- 更新CogVideoX-Fun-V1.0版本:创建代码!现在支持 Windows 和 Linux。支持2b与5b最大256x256x49到1024x1024x49的任意分辨率的视频生成。[2024.09.18]
|
||||
# 二、快速开始与使用
|
||||
|
||||
功能概览:
|
||||
- [数据预处理](#data-preprocess)
|
||||
- [训练DiT](#dit-train)
|
||||
- [模型生成](#video-gen)
|
||||
<a id="quick-start"></a>
|
||||
|
||||
我们的ui界面如下:
|
||||

|
||||
## 1. 环境准备
|
||||
|
||||
# 快速启动
|
||||
### 1. 云使用: AliyunDSW/Docker
|
||||
#### a. 通过阿里云 DSW
|
||||
### 1.1 云使用: AliyunDSW
|
||||
DSW 有免费 GPU 时间,用户可申请一次,申请后3个月内有效。
|
||||
|
||||
阿里云在[Freetier](https://free.aliyun.com/?product=9602825&crowd=enterprise&spm=5176.28055625.J_5831864660.1.e939154aRgha4e&scm=20140722.M_9974135.P_110.MO_1806-ID_9974135-MID_9974135-CID_30683-ST_8512-V_1)提供免费GPU时间,获取并在阿里云PAI-DSW中使用,5分钟内即可启动CogVideoX-Fun。
|
||||
阿里云在[Freetier](https://free.aliyun.com/?product=9602825&crowd=enterprise&spm=5176.28055625.J_5831864660.1.e939154aRgha4e&scm=20140722.M_9974135.P_110.MO_1806-ID_9974135-MID_9974135-CID_30683-ST_8512-V_1)提供免费GPU时间,获取并在阿里云PAI-DSW中使用,5分钟内即可启动VideoX-Fun。
|
||||
|
||||
[](https://gallery.pai-ml.com/#/preview/deepLearning/cv/cogvideox_fun)
|
||||
|
||||
#### b. 通过ComfyUI
|
||||
我们的ComfyUI界面如下,具体查看[ComfyUI README](comfyui/README.md)。
|
||||

|
||||
### 1.2 本地依赖安装
|
||||
|
||||
#### c. 通过docker
|
||||
使用docker的情况下,请保证机器中已经正确安装显卡驱动与CUDA环境,然后以此执行以下命令:
|
||||
|
||||
```
|
||||
# pull image
|
||||
docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# enter image
|
||||
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# clone code
|
||||
git clone https://github.com/aigc-apps/VideoX-Fun.git
|
||||
|
||||
# enter VideoX-Fun's dir
|
||||
cd VideoX-Fun
|
||||
|
||||
# download weights
|
||||
mkdir models/Diffusion_Transformer
|
||||
mkdir models/Personalized_Model
|
||||
|
||||
# Please use the hugginface link or modelscope link to download the model.
|
||||
# CogVideoX-Fun
|
||||
# https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP
|
||||
# https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP
|
||||
|
||||
# Wan
|
||||
# https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP
|
||||
# https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP
|
||||
```
|
||||
|
||||
### 2. 本地安装: 环境检查/下载/安装
|
||||
#### a. 环境检查
|
||||
我们已验证该库可在以下环境中执行:
|
||||
|
||||
Windows 的详细信息:
|
||||
@@ -105,12 +58,71 @@ Linux 的详细信息:
|
||||
- pytorch: torch2.2.0
|
||||
- CUDA: 11.8 & 12.1
|
||||
- CUDNN: 8+
|
||||
- GPU:Nvidia-V100 16G & Nvidia-A10 24G & Nvidia-A100 40G & Nvidia-A100 80G
|
||||
- GPU:Nvidia-V100 16G & Nvidia-A10 24G & Nvidia-A100 40G & Nvidia-A100 80G & Nvidia-H800 80G
|
||||
|
||||
我们需要大约 60GB 的可用磁盘空间,请检查!
|
||||
**方式一:使用requirements.txt**
|
||||
|
||||
#### b. 权重放置
|
||||
我们最好将[权重](#model-zoo)按照指定路径进行放置:
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
**方式二:手动安装依赖**
|
||||
|
||||
```bash
|
||||
# 核心依赖,与requirements.txt保持一致
|
||||
pip install Pillow einops safetensors timm tomesd albumentations librosa "torch>=2.1.2" torchdiffeq torchsde decord datasets numpy scikit-image
|
||||
pip install omegaconf SentencePiece imageio[ffmpeg] imageio[pyav] tensorboard beautifulsoup4 ftfy func_timeout onnxruntime
|
||||
pip install "peft>=0.17.0" "accelerate>=0.25.0" "gradio>=3.41.2" "diffusers>=0.30.1" "transformers>=4.46.2"
|
||||
# 权重下载
|
||||
pip install modelscope
|
||||
# 多卡并行推理需要,推荐固定版本,单卡可跳过
|
||||
pip install "xfuser==0.4.2"
|
||||
# opencv统一使用headless版本,避免部分环境下的GUI依赖
|
||||
pip uninstall opencv-python opencv-contrib-python opencv-python-headless -y
|
||||
pip install opencv-python-headless
|
||||
# 训练可选:DeepSpeed训练需要,固定numpy版本以避免兼容性问题
|
||||
pip install deepspeed==0.17.0 numpy==1.26.4
|
||||
# 加速可选:安装后注意力自动使用Flash Attention后端,未安装时回退到SDPA
|
||||
pip install flash-attn --no-build-isolation
|
||||
```
|
||||
|
||||
> 说明:`torch`与`flash-attn`建议按照本机的CUDA版本从官方渠道安装指定版本,国内网络可追加`-i https://mirrors.aliyun.com/pypi/simple/`加速,具体依赖请以[requirements.txt](requirements.txt)为准。
|
||||
|
||||
### 1.3 使用Docker
|
||||
使用docker的情况下,请保证机器中已经正确安装显卡驱动与CUDA环境,然后以此执行以下命令:
|
||||
|
||||
```
|
||||
# pull image
|
||||
docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# enter image
|
||||
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# clone code
|
||||
git clone https://github.com/aigc-apps/VideoX-Fun.git
|
||||
|
||||
# enter VideoX-Fun's dir
|
||||
cd VideoX-Fun
|
||||
```
|
||||
|
||||
### 1.4 权重放置
|
||||
我们最好将[权重](#三已支持的模型)按照指定路径进行放置:
|
||||
|
||||
**运行自身的python文件或ui界面**:
|
||||
```
|
||||
📦 models/
|
||||
├── 📂 Diffusion_Transformer/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
|
||||
│ ├── 📂 Wan2.1-Fun-V1.1-14B-InP
|
||||
│ ├── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
|
||||
│ ├── 📂 Z-Image/
|
||||
│ └── 📂 Qwen-Image/
|
||||
├── 📂 Personalized_Model/
|
||||
│ └── your trained trainformer model / your trained lora model (for UI load)
|
||||
```
|
||||
|
||||
视频模型与图片模型的权重均统一放在`models/Diffusion_Transformer/`下,文件夹名与[已支持的模型](#三已支持的模型)中的权重名保持一致。
|
||||
|
||||
**通过comfyui**:
|
||||
将模型放入Comfyui的权重文件夹`ComfyUI/models/Fun_Models/`:
|
||||
@@ -124,297 +136,42 @@ Linux 的详细信息:
|
||||
│ └── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
|
||||
```
|
||||
|
||||
**运行自身的python文件或ui界面**:
|
||||
```
|
||||
📦 models/
|
||||
├── 📂 Diffusion_Transformer/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
|
||||
│ ├── 📂 Wan2.1-Fun-V1.1-14B-InP
|
||||
│ └── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
|
||||
├── 📂 Personalized_Model/
|
||||
│ └── your trained trainformer model / your trained lora model (for UI load)
|
||||
```
|
||||
## 2. 推理生成
|
||||
|
||||
# 视频作品
|
||||
<a id="video-gen"></a>
|
||||
视频模型与图片模型的推理入口完全一致,均由`examples/{model_name}/`下的脚本或界面提供,模型清单见[已支持的模型](#三已支持的模型)。
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-InP && Wan2.1-Fun-V1.1-1.3B-InP
|
||||
### 2.1 入口选择
|
||||
| 使用入口 | 适合场景 | 可配置粒度 |
|
||||
|--|--|--|
|
||||
| python文件 | 批量生成、参数写在脚本里调试 | 全量参数,含`GPU_memory_mode`、`transformer_path`、`lora_path` |
|
||||
| webui | 交互体验、快速切换模型 | 常见参数,显存方案仅4档,见2.2 |
|
||||
| ComfyUI | 已有ComfyUI工作流、节点化组合 | 节点参数,权重放置见1.5 |
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
### 2.2 显存节省方案
|
||||
基线模型的参数量普遍很大,为适应消费级显卡,每个预测文件都提供了GPU_memory_mode,视频模型与图片模型通用。可选项按省显存程度从高到低排列,与代码中的判断顺序一致:
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
|
||||
|
||||
Generic Control Video + Reference Image:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Reference Image
|
||||
</td>
|
||||
<td>
|
||||
Control Video
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-14B-Control
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-1.3B-Control
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</table>
|
||||
|
||||
|
||||
Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</table>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Pan Up
|
||||
</td>
|
||||
<td>
|
||||
Pan Left
|
||||
</td>
|
||||
<td>
|
||||
Pan Right
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
Pan Down
|
||||
</td>
|
||||
<td>
|
||||
Pan Up + Pan Left
|
||||
</td>
|
||||
<td>
|
||||
Pan Up + Pan Right
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B
|
||||
|
||||
Resolution-1024
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
Resolution-768
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
Resolution-512
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B-Control
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
A young woman with beautiful clear eyes and blonde hair, wearing white clothes and twisting her body, with the camera focused on her face. High quality, masterpiece, best quality, high resolution, ultra-fine, dreamlike.
|
||||
</td>
|
||||
<td>
|
||||
A young woman with beautiful clear eyes and blonde hair, wearing white clothes and twisting her body, with the camera focused on her face. High quality, masterpiece, best quality, high resolution, ultra-fine, dreamlike.
|
||||
</td>
|
||||
<td>
|
||||
A young bear.
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
# 如何使用
|
||||
|
||||
<h3 id="video-gen">1. 生成 </h3>
|
||||
|
||||
#### a、显存节省方案
|
||||
由于Wan2.1的参数非常大,我们需要考虑显存节省方案,以节省显存适应消费级显卡。我们给每个预测文件都提供了GPU_memory_mode,可以在model_cpu_offload,model_cpu_offload_and_qfloat8,sequential_cpu_offload中进行选择。该方案同样适用于CogVideoX-Fun的生成。
|
||||
|
||||
- model_cpu_offload代表整个模型在使用后会进入cpu,可以节省部分显存。
|
||||
- model_cpu_offload_and_qfloat8代表整个模型在使用后会进入cpu,并且对transformer模型进行了float8的量化,可以节省更多的显存。
|
||||
- sequential_cpu_offload代表模型的每一层在使用后会进入cpu,速度较慢,节省大量显存。
|
||||
- sequential_cpu_offload:模型的每一层在使用后会进入cpu,速度较慢,节省大量显存。
|
||||
- model_group_offload:以leaf层级在cpu与gpu之间搬运权重,并借助stream异步预取,兼顾速度与显存。
|
||||
- model_cpu_offload_and_qfloat8:整个模型在使用后会进入cpu,并且对transformer模型进行了float8的量化,可以节省更多的显存。
|
||||
- model_cpu_offload:整个模型在使用后会进入cpu,可以节省部分显存。
|
||||
- model_full_load_and_qfloat8:模型常驻gpu,仅对transformer做float8量化,显存临界且对速度要求较高时可选。
|
||||
- 默认(传入model_full_load或其他取值):模型全部进入gpu,速度最快,显存需求最高。
|
||||
|
||||
qfloat8会部分降低模型的性能,但可以节省更多的显存。如果显存足够,推荐使用model_cpu_offload。
|
||||
|
||||
#### b、通过comfyui
|
||||
具体查看[ComfyUI README](comfyui/README.md)。
|
||||
> 注意:`app.py`中仅提供model_full_load、model_cpu_offload、model_cpu_offload_and_qfloat8、sequential_cpu_offload四种模式,`model_group_offload`与`model_full_load_and_qfloat8`需在python预测文件中使用;另外compile类加速与`sequential_cpu_offload`、fsdp_dit不兼容。
|
||||
|
||||
#### c、运行python文件
|
||||
### 2.3 通过python文件
|
||||
推理脚本统一命名为`predict_{任务}.py`,在脚本内修改`model_name`、prompt等参数后直接运行,结果保存到脚本中`save_path`指定的目录。视频模型与图片模型的差别只在任务后缀,例如`examples/cogvideox_fun/predict_t2v.py`、`examples/wan2.2_fun/predict_i2v.py`与`examples/z_image/predict_t2i.py`、`examples/qwenimage/predict_t2i_edit.py`。具体某个模型支持哪些任务,以`examples/{model_name}/`下实际存在的脚本为准。
|
||||
|
||||
##### i、单卡运行:
|
||||
**i、单卡运行**:以CogVideoX-Fun为例。
|
||||
|
||||
- 步骤1:下载对应[权重](#model-zoo)放入models文件夹。
|
||||
- 步骤2:根据不同的权重与预测目标使用不同的文件进行预测。当前该库支持CogVideoX-Fun、Wan2.1和Wan2.1-Fun,在examples文件夹下用文件夹名以区分,不同模型支持的功能不同,请视具体情况予以区分。以CogVideoX-Fun为例。
|
||||
- 步骤1:下载对应[权重](#三已支持的模型)并按1.5放入models文件夹。
|
||||
- 步骤2:根据不同的权重与预测目标使用不同的文件进行预测。
|
||||
- 文生视频:
|
||||
- 使用examples/cogvideox_fun/predict_t2v.py文件中修改prompt、neg_prompt、guidance_scale和seed。
|
||||
- 而后运行examples/cogvideox_fun/predict_t2v.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos文件夹中。
|
||||
- 而后运行examples/cogvideox_fun/predict_t2v.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos-t2v文件夹中。
|
||||
- 图生视频:
|
||||
- 使用examples/cogvideox_fun/predict_i2v.py文件中修改validation_image_start、validation_image_end、prompt、neg_prompt、guidance_scale和seed。
|
||||
- validation_image_start是视频的开始图片,validation_image_end是视频的结尾图片。
|
||||
@@ -426,15 +183,11 @@ qfloat8会部分降低模型的性能,但可以节省更多的显存。如果
|
||||
- 普通控制生视频(Canny、Pose、Depth等):
|
||||
- 使用examples/cogvideox_fun/predict_v2v_control.py文件中修改control_video、validation_image_end、prompt、neg_prompt、guidance_scale和seed。
|
||||
- control_video是控制生视频的控制视频,是使用Canny、Pose、Depth等算子提取后的视频。您可以使用以下视频运行演示:[演示视频](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/pose.mp4)
|
||||
- 而后运行examples/cogvideox_fun/predict_v2v_control.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos_v2v_control文件夹中。
|
||||
- 步骤3:如果想结合自己训练的其他backbone与Lora,则看情况修改examples/{model_name}/predict_t2v.py中的examples/{model_name}/predict_i2v.py和lora_path。
|
||||
- 而后运行examples/cogvideox_fun/predict_v2v_control.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos_control文件夹中。
|
||||
- 步骤3:如果想结合自己训练的其他backbone与Lora,则在对应的`examples/{model_name}/predict_*.py`中设置`transformer_path`与`lora_path`(Wan2.2双 Transformer模型另有`transformer_high_path`与`lora_high_path`,分别对应high noise阶段)。
|
||||
|
||||
##### ii、多卡运行:
|
||||
在使用多卡预测时请注意安装xfuser仓库,推荐安装xfuser==0.4.2和yunchang==0.6.2。
|
||||
```
|
||||
pip install xfuser==0.4.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
pip install yunchang==0.6.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
```
|
||||
**ii、多卡运行**:
|
||||
多卡并行推理所需的`xfuser`已列入1.3,推荐固定为`xfuser==0.4.2`。
|
||||
|
||||
请确保ulysses_degree和ring_degree的乘积等于使用的GPU数量。例如,如果您使用8个GPU,则可以设置ulysses_degree=2和ring_degree=4,也可以设置ulysses_degree=4和ring_degree=2。
|
||||
|
||||
@@ -449,21 +202,25 @@ ulysses_degree是在head进行切分后并行生成,ring_degree是在sequence
|
||||
torchrun --nproc-per-node=8 examples/wan2.1_fun/predict_t2v.py
|
||||
```
|
||||
|
||||
#### d、通过ui界面
|
||||
### 2.4 通过ui界面
|
||||
webui支持文生视频、图生视频、视频生视频和普通控制生视频(Canny、Pose、Depth等)。当前提供`app.py`的是CogVideoX-Fun、Wan2.1、Wan2.1-Fun、Wan2.2、Wan2.2-Fun(界面实现位于`videox_fun/ui/`),其余模型(包含图片模型)请使用python文件进行预测。以CogVideoX-Fun为例。
|
||||
|
||||
webui支持文生视频、图生视频、视频生视频和普通控制生视频(Canny、Pose、Depth等)。当前该库支持CogVideoX-Fun、Wan2.1和Wan2.1-Fun,在examples文件夹下用文件夹名以区分,不同模型支持的功能不同,请视具体情况予以区分。以CogVideoX-Fun为例。
|
||||
|
||||
- 步骤1:下载对应[权重](#model-zoo)放入models文件夹。
|
||||
- 步骤1:下载对应[权重](#三已支持的模型)并按1.5放入models文件夹。
|
||||
- 步骤2:运行examples/cogvideox_fun/app.py文件,进入gradio页面。
|
||||
- 步骤3:根据页面选择生成模型,填入prompt、neg_prompt、guidance_scale和seed等,点击生成,等待生成结果,结果保存在sample文件夹中。
|
||||
|
||||
### 2. 模型训练
|
||||
一个完整的模型训练链路应该包括数据预处理和Video DiT训练。不同模型的训练流程类似,数据格式也类似:
|
||||
### 2.5 通过ComfyUI
|
||||
具体查看[ComfyUI README](comfyui/README.md),我们的ComfyUI界面如下:
|
||||

|
||||
|
||||
<h4 id="data-preprocess">a.数据预处理</h4>
|
||||
我们给出了一个简单的demo通过图片数据训练lora模型,详情可以查看[wiki](https://github.com/aigc-apps/CogVideoX-Fun/wiki/Training-Lora)。
|
||||
## 3. 模型训练
|
||||
一个完整的模型训练链路应该包括数据预处理和Video DiT训练。不同模型的训练流程类似,数据格式也类似。
|
||||
|
||||
一个完整的长视频切分、清洗、描述的数据预处理链路可以参考video caption部分的[README](cogvideox/video_caption/README.md)进行。
|
||||
<a id="data-preprocess"></a>
|
||||
### 3.1 数据预处理
|
||||
各模型的 LoRA 训练文档统一放在 `scripts/{model_name}/` 下,中文版以 `_zh-CN` 结尾,详情见[3.3 各模型训练文档](#33-各模型训练文档)。
|
||||
|
||||
一个完整的长视频切分、清洗、描述的数据预处理链路可以参考video caption部分的[README](videox_fun/video_caption/README_zh-CN.md)进行。
|
||||
|
||||
如果期望训练一个文生图视频的生成模型,您需要以这种格式排列数据集。
|
||||
```
|
||||
@@ -510,187 +267,229 @@ json_of_internal_datasets.json是一个标准的json文件。json中的file_path
|
||||
.....
|
||||
]
|
||||
```
|
||||
<h4 id="dit-train">b. Video DiT训练 </h4>
|
||||
|
||||
如果数据预处理时,数据的格式为相对路径,则进入scripts/{model_name}/train.sh进行如下设置。
|
||||
<a id="dit-train"></a>
|
||||
### 3.2 Video DiT训练
|
||||
各模型的训练脚本与启动sh均位于`scripts/{model_name}/`下,sh的命名随任务而变,如`train.sh`、`train_lora.sh`、`train_control.sh`、`train_control_distill.sh`等,以目录内实际文件为准。
|
||||
|
||||
如果数据预处理时,数据的格式为相对路径,则进入对应的`scripts/{model_name}/train.sh`进行如下设置。
|
||||
```
|
||||
export DATASET_NAME="datasets/internal_datasets/"
|
||||
export DATASET_META_NAME="datasets/internal_datasets/json_of_internal_datasets.json"
|
||||
```
|
||||
|
||||
如果数据的格式为绝对路径,则进入scripts/train.sh进行如下设置。
|
||||
如果数据的格式为绝对路径,则在同一个脚本中设置如下(此时`DATASET_NAME`置空,不再拼接数据集目录前缀)。
|
||||
```
|
||||
export DATASET_NAME=""
|
||||
export DATASET_META_NAME="/mnt/data/json_of_internal_datasets.json"
|
||||
```
|
||||
|
||||
最后运行scripts/train.sh。
|
||||
最后运行对应的脚本。
|
||||
```sh
|
||||
sh scripts/train.sh
|
||||
sh scripts/{model_name}/train.sh
|
||||
```
|
||||
|
||||
关于一些参数的设置细节:
|
||||
Wan2.1-Fun可以查看[Readme Train](scripts/wan2.1_fun/README_TRAIN.md)与[Readme Lora](scripts/wan2.1_fun/README_TRAIN_LORA.md)。
|
||||
Wan2.1可以查看[Readme Train](scripts/wan2.1/README_TRAIN.md)与[Readme Lora](scripts/wan2.1/README_TRAIN_LORA.md)。
|
||||
CogVideoX-Fun可以查看[Readme Train](scripts/cogvideox_fun/README_TRAIN.md)与[Readme Lora](scripts/cogvideox_fun/README_TRAIN_LORA.md)。
|
||||
### 3.3 各模型训练文档
|
||||
关于参数设置细节,各模型的训练文档统一放在`scripts/{model_name}/`下,`README_TRAIN*`为基线训练,`README_TRAIN_LORA*`为LoRA训练,`README_TRAIN_CONTROL*`为控制训练,中文版以`_zh-CN`结尾。常用模型如下:
|
||||
|
||||
|
||||
# 模型地址
|
||||
## 1.Wan2.2-Fun
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.2-Fun-A14B-InP | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-InP) | Wan2.2-Fun-14B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.2-Fun-A14B-Control | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control)| Wan2.2-Fun-14B视频控制权重,支持不同的控制条件,如Canny、Depth、Pose、MLSD等,同时支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.2-Fun-A14B-Control-Camera | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control-Camera)| Wan2.2-Fun-14B相机镜头控制权重。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.2-VACE-Fun-A14B | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-VACE-Fun-A14B) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-VACE-Fun-A14B)| 以VACE方案训练的Wan2.2控制权重,基础模型为Wan2.2-T2V-A14B,支持不同的控制条件,如Canny、Depth、Pose、MLSD、轨迹控制等。支持通过主体指定生视频。支持多分辨率(512,768,1024)的视频预测,支持多分辨率(512,768,1024)的视频预测,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.2-Fun-5B-InP | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-InP) | Wan2.2-Fun-5B文图生视频权重,以121帧、每秒24帧进行训练支持首尾图预测。 |
|
||||
| Wan2.2-Fun-5B-Control | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control)| Wan2.2-Fun-5B视频控制权重,支持不同的控制条件,如Canny、Depth、Pose、MLSD等,同时支持使用轨迹控制。以121帧、每秒24帧进行训练,支持多语言预测 |
|
||||
| Wan2.2-Fun-5B-Control-Camera | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control-Camera)| Wan2.2-Fun-5B相机镜头控制权重。以121帧、每秒24帧进行训练,支持多语言预测 |
|
||||
|
||||
## 2. Wan2.2
|
||||
|
||||
| 名称 | Hugging Face | Model Scope | 描述 |
|
||||
| 模型 | 基线训练 | LoRA训练 | 其他 |
|
||||
|--|--|--|--|
|
||||
| Wan2.2-TI2V-5B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-TI2V-5B) | 万象2.2-5B文生视频权重 |
|
||||
| Wan2.2-T2V-A14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-T2V-A14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-T2V-A14B) | 万象2.2-14B文生视频权重 |
|
||||
| Wan2.2-I2V-A14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-I2V-A14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-I2V-A14B) | 万象2.2-14B图生视频权重 |
|
||||
| Wan2.1-Fun | [中文](scripts/wan2.1_fun/README_TRAIN_zh-CN.md) / [EN](scripts/wan2.1_fun/README_TRAIN.md) | [中文](scripts/wan2.1_fun/README_TRAIN_LORA_zh-CN.md) / [EN](scripts/wan2.1_fun/README_TRAIN_LORA.md) | [Control 中文](scripts/wan2.1_fun/README_TRAIN_CONTROL_zh-CN.md)、[Reward LoRA](scripts/wan2.1_fun/README_TRAIN_REWARD.md) |
|
||||
| Wan2.2 | [中文](scripts/wan2.2/README_TRAIN_zh-CN.md) / [EN](scripts/wan2.2/README_TRAIN.md) | [中文](scripts/wan2.2/README_TRAIN_LORA_zh-CN.md) / [EN](scripts/wan2.2/README_TRAIN_LORA.md) | [蒸馏 中文](scripts/wan2.2/README_TRAIN_DISTILL_zh-CN.md)、[S2V](scripts/wan2.2/README_TRAIN_S2V_zh-CN.md)、[Animate](scripts/wan2.2/README_TRAIN_ANIMATE.md) |
|
||||
| Wan2.2-Fun | [中文](scripts/wan2.2_fun/README_TRAIN_zh-CN.md) / [EN](scripts/wan2.2_fun/README_TRAIN.md) | [中文](scripts/wan2.2_fun/README_TRAIN_LORA_zh-CN.md) / [EN](scripts/wan2.2_fun/README_TRAIN_LORA.md) | [Control LoRA 中文](scripts/wan2.2_fun/README_TRAIN_CONTROL_LORA_zh-CN.md) |
|
||||
| CogVideoX-Fun | [中文](scripts/cogvideox_fun/README_TRAIN_zh-CN.md) / [EN](scripts/cogvideox_fun/README_TRAIN.md) | [中文](scripts/cogvideox_fun/README_TRAIN_LORA_zh-CN.md) / [EN](scripts/cogvideox_fun/README_TRAIN_LORA.md) | [Control 中文](scripts/cogvideox_fun/README_TRAIN_CONTROL_zh-CN.md)、[Reward LoRA](scripts/cogvideox_fun/README_TRAIN_REWARD.md) |
|
||||
| Qwen-Image | [中文](scripts/qwenimage/README_TRAIN_zh-CN.md) / [EN](scripts/qwenimage/README_TRAIN.md) | [中文](scripts/qwenimage/README_TRAIN_LORA_zh-CN.md) / [EN](scripts/qwenimage/README_TRAIN_LORA.md) | [Edit 中文](scripts/qwenimage/README_TRAIN_EDIT_zh-CN.md) |
|
||||
| Qwen-Image-2.1 | [中文](scripts/qwenimage21/README_TRAIN_zh-CN.md) / [EN](scripts/qwenimage21/README_TRAIN.md) | - | - |
|
||||
| Z-Image | [中文](scripts/z_image/README_TRAIN_zh-CN.md) / [EN](scripts/z_image/README_TRAIN.md) | [中文](scripts/z_image/README_TRAIN_LORA_zh-CN.md) / [EN](scripts/z_image/README_TRAIN_LORA.md) | [GRPO LoRA 中文](scripts/z_image/README_TRAIN_GRPO_LORA_zh-CN.md) |
|
||||
|
||||
## 3. Wan2.1-Fun
|
||||
其余模型(如HunyuanVideo、MiniMax-H3、Flux2-Fun、InfiniteTalk、LingBot等)同理,直接查看对应`scripts/{model_name}/`下的README即可。
|
||||
|
||||
V1.1:
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-V1.1-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP) | Wan2.1-Fun-V1.1-1.3B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.1-Fun-V1.1-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP) | Wan2.1-Fun-V1.1-14B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control)| Wan2.1-Fun-V1.1-1.3B视频控制权重支持不同的控制条件,如Canny、Depth、Pose、MLSD等,支持参考图 + 控制条件进行控制,支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control)| Wan2.1-Fun-V1.1-14B视视频控制权重支持不同的控制条件,如Canny、Depth、Pose、MLSD等,支持参考图 + 控制条件进行控制,支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control-Camera | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control-Camera)| Wan2.1-Fun-V1.1-1.3B相机镜头控制权重。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.1-Fun-V1.1-14B-Control-Camera | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control-Camera)| Wan2.1-Fun-V1.1-14B相机镜头控制权重。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
|
||||
V1.0:
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-InP) | Wan2.1-Fun-1.3B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.1-Fun-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP) | Wan2.1-Fun-14B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.1-Fun-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-Control)| Wan2.1-Fun-1.3B视频控制权重,支持不同的控制条件,如Canny、Depth、Pose、MLSD等,同时支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.1-Fun-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-Control)| Wan2.1-Fun-14B视频控制权重,支持不同的控制条件,如Canny、Depth、Pose、MLSD等,同时支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
# 三、已支持的模型
|
||||
下表按模型系列汇总目前已支持的权重,视频模型与图片模型共用同一套推理与训练入口。每个系列一行,第四列为内嵌的四列表格,依次为权重、Hugging Face、ModelScope、对应说明;🤗 为 Hugging Face、🤖 为 ModelScope(国内网络推荐),`-` 表示该渠道确认无对应仓库或需登录授权。各模型训练文档见[3.3 各模型训练文档](#33-各模型训练文档)。
|
||||
|
||||
## 4. Wan2.1
|
||||
|
||||
| 名称 | Hugging Face | Model Scope | 描述 |
|
||||
| 模型系列 | 模态 | 支持任务 | 权重 / 下载 / 说明 |
|
||||
|--|--|--|--|
|
||||
| Wan2.1-T2V-1.3B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-1.3B) | 万象2.1-1.3B文生视频权重 |
|
||||
| Wan2.1-T2V-14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-14B) | 万象2.1-14B文生视频权重 |
|
||||
| Wan2.1-I2V-14B-480P | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-480P) | 万象2.1-14B-480P图生视频权重 |
|
||||
| Wan2.1-I2V-14B-720P| [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | 万象2.1-14B-720P图生视频权重 |
|
||||
| Wan2.2-Fun | 视频 | 本项目在Wan2.2上训练的系列,覆盖文生视频、图生视频、首尾图、控制生成、相机控制 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-A14B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">14B MoE双阶段文/图生视频,多分辨率训练、81帧16fps,支持首尾图</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-A14B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">14B控制生成,支持Canny、Depth、Pose、MLSD与轨迹控制</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-A14B-Control-Camera</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control-Camera">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control-Camera">🤖</a></td><td valign="top" style="padding:2px 0;">在14B Control基础上增加相机运动控制</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-5B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">5B统一VAE文/图生视频,121帧24fps,支持首尾图</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-5B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">5B控制生成,控制条件与14B一致</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-5B-Control-Camera</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control-Camera">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control-Camera">🤖</a></td><td valign="top" style="padding:2px 0;">5B相机运动控制</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Fun-Reward-LoRAs</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-Fun-Reward-LoRAs">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-Fun-Reward-LoRAs">🤖</a></td><td valign="top" style="padding:2px 0;">奖励反向传播训练的对齐LoRA,叠加在上述权重上使用</td></tr></table> |
|
||||
| Wan2.2-VACE-Fun | 视频 | 本项目以VACE方案训练的系列,覆盖控制生成、主体参考 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-VACE-Fun-A14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.2-VACE-Fun-A14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.2-VACE-Fun-A14B">🤖</a></td><td valign="top" style="padding:2px 0;">以Wan2.2-T2V-A14B为基础,支持Canny、Depth、Pose、MLSD、轨迹控制与主体参考生视频</td></tr></table> |
|
||||
| Wan2.2 | 视频 | 万象官方权重,覆盖文生视频、图生视频、音频驱动、角色动画,可作为Wan2.2-Fun系列的训练基线 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-TI2V-5B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.2-TI2V-5B">🤖</a></td><td valign="top" style="padding:2px 0;">5B统一VAE,文生图生视频通用权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-T2V-A14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-T2V-A14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.2-T2V-A14B">🤖</a></td><td valign="top" style="padding:2px 0;">14B MoE文生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-I2V-A14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-I2V-A14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.2-I2V-A14B">🤖</a></td><td valign="top" style="padding:2px 0;">14B MoE图生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-S2V-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-S2V-14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Wan-AI/Wan2.2-S2V-14B">🤖</a></td><td valign="top" style="padding:2px 0;">语音驱动数字人</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.2-Animate-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.2-Animate-14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Wan-AI/Wan2.2-Animate-14B">🤖</a></td><td valign="top" style="padding:2px 0;">角色替换与动作迁移,仓库含多精度文件</td></tr></table> |
|
||||
| Wan2.1-Fun V1.1 | 视频 | 本项目在Wan2.1上训练的V1.1版本,多分辨率(512/768/1024)、81帧16fps,覆盖文生视频、图生视频、首尾图、控制生成、相机控制 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-1.3B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">1.3B轻量文/图生视频,支持首尾图</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-14B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">14B文/图生视频,支持首尾图</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-1.3B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">1.3B控制生成,同时支持参考图+控制条件组合</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-14B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">14B控制生成,同时支持参考图+控制条件组合</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-1.3B-Control-Camera</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control-Camera">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control-Camera">🤖</a></td><td valign="top" style="padding:2px 0;">1.3B相机运动控制</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-V1.1-14B-Control-Camera</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control-Camera">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control-Camera">🤖</a></td><td valign="top" style="padding:2px 0;">14B相机运动控制</td></tr></table> |
|
||||
| Wan2.1-Fun V1.0 | 视频 | 本项目在Wan2.1上训练的V1.0版本,能力与V1.1相同但无相机控制 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-1.3B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">V1.0的1.3B文/图生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-14B-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP">🤖</a></td><td valign="top" style="padding:2px 0;">V1.0的14B文/图生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-1.3B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">V1.0的1.3B控制生成</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-14B-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-Control">🤖</a></td><td valign="top" style="padding:2px 0;">V1.0的14B控制生成</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-Fun-Reward-LoRAs</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Wan2.1-Fun-Reward-LoRAs">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Wan2.1-Fun-Reward-LoRAs">🤖</a></td><td valign="top" style="padding:2px 0;">奖励反向传播训练的对齐LoRA</td></tr></table> |
|
||||
| Wan2.1 | 视频 | 万象官方权重,覆盖文生视频、图生视频、控制生成,可作为Wan2.1-Fun系列的训练基线 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-T2V-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-1.3B">🤖</a></td><td valign="top" style="padding:2px 0;">1.3B文生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-T2V-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-T2V-14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-14B">🤖</a></td><td valign="top" style="padding:2px 0;">14B文生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-I2V-14B-480P</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-480P">🤖</a></td><td valign="top" style="padding:2px 0;">480P图生视频,是InfiniteTalk的基础模型</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-I2V-14B-720P</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P">🤖</a></td><td valign="top" style="padding:2px 0;">720P图生视频,是FantasyTalking的基础模型</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-VACE-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-VACE-1.3B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Wan-AI/Wan2.1-VACE-1.3B">🤖</a></td><td valign="top" style="padding:2px 0;">1.3B VACE控制与主体参考</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Wan2.1-VACE-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Wan-AI/Wan2.1-VACE-14B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Wan-AI/Wan2.1-VACE-14B">🤖</a></td><td valign="top" style="padding:2px 0;">14B VACE控制与主体参考</td></tr></table> |
|
||||
| Self-Forcing / Causal-Forcing / Flex-Forcing | 视频 | 自回归蒸馏方案,覆盖流式生成、交互式生成与分块注意力 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Self-Forcing</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/gdhe17/Self-Forcing">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/AI-ModelScope/Self-Forcing">🤖</a></td><td valign="top" style="padding:2px 0;">官方发布的蒸馏权重,配合Wan2.1-T2V使用;也可由`scripts/wan2.1_self_forcing`与`scripts/wan2.1_causal_forcing`自行训练得到;Flex-Forcing(分块因果/双向注意力)权重由`scripts/wan2.1_flex_forcing`训练产出</td></tr></table> |
|
||||
| TurboWan / TurboDiffusion | 视频 | TurboDiffusion方案公开发布的少步蒸馏权重 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">TurboWan2.1-T2V-1.3B-480P</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/TurboDiffusion/TurboWan2.1-T2V-1.3B-480P">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/TurboDiffusion/TurboWan2.1-T2V-1.3B-480P">🤖</a></td><td valign="top" style="padding:2px 0;">1.3B文生视频蒸馏权重,官方以.pth发布,仓库另含量化版</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">TurboWan2.2-I2V-A14B-720P</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/TurboDiffusion/TurboWan2.2-I2V-A14B-720P">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/TurboDiffusion/TurboWan2.2-I2V-A14B-720P">🤖</a></td><td valign="top" style="padding:2px 0;">14B图生视频蒸馏权重,仓库含low/high两档噪声模型(另含量化版),放入Personalized_Model后按预测脚本的transformer_path/transformer_high_path引用</td></tr></table> |
|
||||
| CogVideoX-Fun V1.5 | 视频 | V1.5官方权重,多分辨率(512/768/1024)、85帧8fps,覆盖图生视频、奖励对齐 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.5-5b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-5b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-5b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">5b图生视频权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.5-Reward-LoRAs</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-Reward-LoRAs">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs">🤖</a></td><td valign="top" style="padding:2px 0;">奖励反向传播训练的对齐LoRA</td></tr></table> |
|
||||
| CogVideoX-Fun V1.1 | 视频 | V1.1官方权重,多分辨率(512/768/1024/1280)、49帧8fps,覆盖图生视频、姿态控制、控制生成、奖励对齐 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-2b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">2b图生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-5b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">5b图生视频,添加Noise,运动幅度大于V1.0</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-2b-Pose</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Pose">🤖</a></td><td valign="top" style="padding:2px 0;">2b姿态控制</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-5b-Pose</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Pose">🤖</a></td><td valign="top" style="padding:2px 0;">5b姿态控制</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-2b-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Control">🤖</a></td><td valign="top" style="padding:2px 0;">2b控制生成,支持Canny、Depth、Pose、MLSD</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-5b-Control</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Control">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Control">🤖</a></td><td valign="top" style="padding:2px 0;">5b控制生成,支持Canny、Depth、Pose、MLSD</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-V1.1-Reward-LoRAs</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-Reward-LoRAs">🤖</a></td><td valign="top" style="padding:2px 0;">奖励反向传播训练的对齐LoRA</td></tr></table> |
|
||||
| CogVideoX-Fun V1.0 | 视频 | 旧版权重,仍以49帧8fps训练,已被V1.1/V1.5取代 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-2b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-2b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">V1.0的2b图生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">CogVideoX-Fun-5b-InP</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/CogVideoX-Fun-5b-InP">🤖</a></td><td valign="top" style="padding:2px 0;">V1.0的5b图生视频</td></tr></table> |
|
||||
| HunyuanVideo | 视频 | 官方diffusers格式权重,本项目直接支持预测与LoRA训练 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">HunyuanVideo</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/hunyuanvideo-community/HunyuanVideo">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Tencent-Hunyuan/HunyuanVideo">🤖</a></td><td valign="top" style="padding:2px 0;">文生视频</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">HunyuanVideo-I2V</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/hunyuanvideo-community/HunyuanVideo-I2V">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Tencent-Hunyuan/HunyuanVideo-I2V">🤖</a></td><td valign="top" style="padding:2px 0;">图生视频</td></tr></table> |
|
||||
| MiniMax-H3 | 视频 | 官方视频生成权重与本项目训练的ControlNet | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">MiniMax-H3</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/MiniMaxAI/MiniMax-H3">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/MiniMax/MiniMax-H3">🤖</a></td><td valign="top" style="padding:2px 0;">官方基线权重,仓库含多种精度与组件,可按需下载</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">MiniMax-H3-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/MiniMax-H3-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/MiniMax-H3-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">本项目训练的ControlNet,支持多种控制条件与轨迹控制</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">MiniMax-H3-Fun-Controlnet-Union-2.0</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/MiniMax-H3-Fun-Controlnet-Union-2.0">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/MiniMax-H3-Fun-Controlnet-Union-2.0">🤖</a></td><td valign="top" style="padding:2px 0;">本项目训练的ControlNet(2.0版),支持多种控制条件、轨迹控制与inpaint权重</td></tr></table> |
|
||||
| TaoMate-H3 | 视频+音频 | 基于MiniMax-H3的官方流式音视频生成适配器 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">TaoMate-H3-Adapter</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/TaoLiveAIGC/TaoMate-H3">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/TaoLiveAIGC/TaoMate-H3">🤖</a></td><td valign="top" style="padding:2px 0;">官方rank 128适配器(step-3000 EMA),内置3步蒸馏采样调度,支持流式语音驱动生成;需搭配MiniMax-H3基座权重使用</td></tr></table> |
|
||||
| LTX-2 | 视频+音频 | 官方DiT音视频联合生成权重 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">LTX-2</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Lightricks/LTX-2">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Lightricks/LTX-2">🤖</a></td><td valign="top" style="padding:2px 0;">音视频联合生成的官方权重,仓库含多种精度</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">LTX-2.3-Diffusers</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/dg845/LTX-2.3-Diffusers">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">2.3版本需使用社区转换的diffusers格式权重,官方原始权重见<a href="https://huggingface.co/Lightricks/LTX-2.3">Lightricks/LTX-2.3</a></td></tr></table> |
|
||||
| LongCat-Video | 视频 | 官方长视频生成权重,支持LoRA训练 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">LongCat-Video</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/meituan-longcat/LongCat-Video">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/meituan-longcat/LongCat-Video">🤖</a></td><td valign="top" style="padding:2px 0;">文/图生长视频基线</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">LongCat-Video-Avatar</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/meituan-longcat/LongCat-Video-Avatar">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/meituan-longcat/LongCat-Video-Avatar">🤖</a></td><td valign="top" style="padding:2px 0;">数字人权重</td></tr></table> |
|
||||
| FantasyTalking | 音频驱动视频 | 音频条件增量权重,需搭配基础视频权重与音频编码器 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">FantasyTalking</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/acvlab/FantasyTalking">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/amap_cvlab/FantasyTalking">🤖</a></td><td valign="top" style="padding:2px 0;">需搭配Wan2.1-I2V-14B-720P使用</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">wav2vec2-base-960h</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/facebook/wav2vec2-base-960h">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/AI-ModelScope/wav2vec2-base-960h">🤖</a></td><td valign="top" style="padding:2px 0;">音频编码器,放入基础权重目录并命名为audio_encoder</td></tr></table> |
|
||||
| InfiniteTalk | 音频驱动视频 | 音频条件增量权重,需搭配基础视频权重与音频编码器 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">InfiniteTalk</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/MeiGen-AI/InfiniteTalk">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/MeiGen-AI/InfiniteTalk">🤖</a></td><td valign="top" style="padding:2px 0;">需搭配Wan2.1-I2V-14B-480P使用,仓库含多个版本</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">chinese-wav2vec2-base</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/TencentGameMate/chinese-wav2vec2-base">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/TencentGameMate/chinese-wav2vec2-base">🤖</a></td><td valign="top" style="padding:2px 0;">中文音频编码器</td></tr></table> |
|
||||
| FlashHead | 音频驱动视频 | 官方头部动作数字人权重 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">SoulX-FlashHead-1_3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Soul-AILab/SoulX-FlashHead-1_3B">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Soul-AILab/SoulX-FlashHead-1_3B">🤖</a></td><td valign="top" style="padding:2px 0;">语音驱动头部数字人,同样需要wav2vec音频编码器</td></tr></table> |
|
||||
| MOVA | 视频+音频 | 官方MOVA权重 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">MOVA-360p</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/OpenMOSS-Team/MOVA-360p">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/OpenMOSS/MOVA-360p">🤖</a></td><td valign="top" style="padding:2px 0;">图生视频与音视频联合生成</td></tr></table> |
|
||||
| LingBot | 视频 | 相机可控世界模型,目录结构与Wan2.2-I2V-A14B一致 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-world-base-cam</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-world-base-cam">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-world-base-cam">🤖</a></td><td valign="top" style="padding:2px 0;">相机控制基线权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-video-rewriter-lora</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-video-rewriter-lora">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-video-rewriter-lora">🤖</a></td><td valign="top" style="padding:2px 0;">rewriter LoRA,搭配Qwen3.6-27B生成结构化caption</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-video-dense-1.3b</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-video-dense-1.3b">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-video-dense-1.3b">🤖</a></td><td valign="top" style="padding:2px 0;">1.3B稠密版视频生成权重,1-2卡即可训练</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-video-moe-30b-a3b</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-video-moe-30b-a3b">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-video-moe-30b-a3b">🤖</a></td><td valign="top" style="padding:2px 0;">30B MoE(3B激活)视频生成权重,训练建议8×80GB及以上</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">lingbot-world-fast</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Robbyant/lingbot-world-fast">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Robbyant/lingbot-world-fast">🤖</a></td><td valign="top" style="padding:2px 0;">蒸馏少步世界模型(transformer共16个分片),VAE/T5复用lingbot-world-base-cam,推理需使用Flow_Unipc采样器</td></tr></table> |
|
||||
| Phantom | 视频 | 多主体参考生视频的增量权重,基于Wan2.1-T2V | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-1.3B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">1.3B版,官方以.pth发布,放入Personalized_Model后按预测脚本的transformer_path引用</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Phantom-Wan-14B</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/bytedance-research/Phantom">🤗</a></td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">14B版,官方以分片safetensors发布</td></tr></table> |
|
||||
| Qwen-Image | 图片 | 官方文生图与图像编辑权重,支持基线与LoRA训练 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image">🤖</a></td><td valign="top" style="padding:2px 0;">文生图基础权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2512">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2512">🤖</a></td><td valign="top" style="padding:2px 0;">文生图更新版本</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Edit-2509</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Edit-2509">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509">🤖</a></td><td valign="top" style="padding:2px 0;">图像编辑更新版本</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-Layered</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-Layered">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-Layered">🤖</a></td><td valign="top" style="padding:2px 0;">图像图层分解权重,可将图像拆分为多个可编辑的RGBA图层</td></tr></table> |
|
||||
| Qwen-Image-2.1 | 图片 | 官方新一代文生图权重,单流block-causal结构,支持前缀KV cache | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen-Image-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen-Image-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">单流block-causal结构,支持全参数训练;前缀KV cache可加速推理</td></tr></table> |
|
||||
| Qwen-Image ControlNet | 图片 | 图片控制生成,支持Canny、Depth、Pose、MLSD、Scribble | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-2512-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">本项目训练的ControlNet</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen-Image-ControlNet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/InstantX/Qwen-Image-ControlNet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/InstantX/Qwen-Image-ControlNet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">InstantX提供的同类型ControlNet</td></tr></table> |
|
||||
| Z-Image | 图片 | 官方文生图权重 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image">🤖</a></td><td valign="top" style="padding:2px 0;">基础版</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Tongyi-MAI/Z-Image-Turbo">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo">🤖</a></td><td valign="top" style="padding:2px 0;">加速版</td></tr></table> |
|
||||
| Z-Image-Fun | 图片 | 本项目在Z-Image上训练的ControlNet与蒸馏LoRA,控制条件支持Canny、Depth、Pose、MLSD、Scribble、Gray | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">基于基础版的ControlNet,2.1版层数更多、训练更充分</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">基于Turbo的ControlNet</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Turbo-Fun-Controlnet-Union-2.1</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1">🤖</a></td><td valign="top" style="padding:2px 0;">基于Turbo的2.1版ControlNet,仓库含多精度文件</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Z-Image-Fun-Lora-Distill</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill">🤖</a></td><td valign="top" style="padding:2px 0;">同时蒸馏步数与CFG,推理仅需8步</td></tr></table> |
|
||||
| Flux | 图片 | 官方FLUX.1/FLUX.2权重与本项目训练的ControlNet | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.1-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.1-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev">🤖</a></td><td valign="top" style="padding:2px 0;">文生图与图像编辑</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/black-forest-labs/FLUX.2-dev">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev">🤖</a></td><td valign="top" style="padding:2px 0;">第二代官方权重</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">FLUX.2-dev-Fun-Controlnet-Union</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union">🤖</a></td><td valign="top" style="padding:2px 0;">本项目为FLUX.2-dev训练的ControlNet,支持Canny、Depth、Pose、MLSD等</td></tr></table> |
|
||||
| ERNIE-Image | 图片 | 百度官方文生图权重 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">ERNIE-Image</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/baidu/ERNIE-Image">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/PaddlePaddle/ERNIE-Image">🤖</a></td><td valign="top" style="padding:2px 0;">单流DiT文生图,Hugging Face为baidu组织、ModelScope为PaddlePaddle组织</td></tr></table> |
|
||||
| Lens | 图片 | 微软官方文生图权重 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">Lens</td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/microsoft/Lens">🤖</a></td><td valign="top" style="padding:2px 0;">3.8B文生图,仓库内含GPT-OSS文本编码器;Hugging Face侧无公开下载仓库,请从ModelScope获取</td></tr></table> |
|
||||
| 辅助模型 | - | 非生成模型,服务于奖励对齐、数据打标与快速解码 | <table style="width:100%;border-collapse:collapse;"><tr><td valign="top" style="padding:2px 8px 2px 0;">HPSv3</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/MizzenAI/HPSv3">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/MizzenAI/HPSv3">🤖</a></td><td valign="top" style="padding:2px 0;">奖励反向传播使用的打分模型</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">Qwen2-VL-7B-Instruct</td><td valign="top" style="padding:2px 8px;"><a href="https://huggingface.co/Qwen/Qwen2-VL-7B-Instruct">🤗</a></td><td valign="top" style="padding:2px 8px;"><a href="https://modelscope.cn/models/Qwen/Qwen2-VL-7B-Instruct">🤖</a></td><td valign="top" style="padding:2px 0;">视频打标流程使用的多模态编码器</td></tr><tr><td valign="top" style="padding:2px 8px 2px 0;">taew2_1 / taew2_2</td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 8px;">-</td><td valign="top" style="padding:2px 0;">Tiny AutoEncoder(约20MB),与Wan2.1/Wan2.2 VAE共享同一latent空间,解码速度约为完整VAE的100倍,用于快速预览与低显存生成;权重来自<a href="https://github.com/madebyollin/taehv">madebyollin/taehv</a></td></tr></table> |
|
||||
|
||||
## 5. FantasyTalking
|
||||
> 补充说明:
|
||||
> - 音频驱动与参考类模型(FantasyTalking、InfiniteTalk、Phantom、TaoMate-H3)本身只是增量权重,必须同时下载表中对应的基础视频权重与音频编码器。
|
||||
> - TurboDiffusion方案已公开发布TurboWan系列蒸馏权重(见上表);Flex-Forcing、PDD等其余蒸馏方案没有公开发布的权重,按`scripts/{model_name}/README_TRAIN*.md`训练后即可得到,可直接填入预测文件中的`transformer_path`。
|
||||
> - 权重名与`models/Diffusion_Transformer/`下的文件夹名一一对应;同一系列内各权重互不通用,需按预测任务选择,若某个权重未在此列出,说明它由本项目训练产出或需从上游官方仓库获取。
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-I2V-14B-720P | - | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | 万象2.1-14B-720P图生视频权重 |
|
||||
| Wav2Vec | - | [🤗Link](https://huggingface.co/facebook/wav2vec2-base-960h) | [😄Link](https://modelscope.cn/models/AI-ModelScope/wav2vec2-base-960h) | Wav2Vec模型,请放在Wan2.1-I2V-14B-720P文件夹下,命名为audio_encoder |
|
||||
| FantasyTalking model | - | [🤗Link](https://huggingface.co/acvlab/FantasyTalking/) | [😄Link](https://www.modelscope.cn/models/amap_cvlab/FantasyTalking/) | 官方Audio Condition的权重。 |
|
||||
# 四、视频作品
|
||||
|
||||
## 6. Qwen-Image
|
||||
图生视频:
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image | [🤗Link](https://huggingface.co/Qwen/Qwen-Image) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image) | Qwen-Image官方权重 |
|
||||
| Qwen-Image-Edit | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit) | Qwen-Image-Edit官方权重 |
|
||||
| Qwen-Image-Edit-2509 | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit-2509) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509) | Qwen-Image-Edit-2509官方权重 |
|
||||
|
||||
## 7. Qwen-Image-Fun
|
||||
|
||||
| 名称 | 存储 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image-2512-Fun-Controlnet-Union | - | [🤗链接](https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union) | [😄链接](https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union) | Qwen-Image-2512的ControlNet权重,支持多种控制条件,如Canny、Depth、Pose、MLSD、Scribble等。 |
|
||||
|
||||
## 8. Z-Image
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image | [🤗Link](https://huggingface.co/Tongyi-MAI/Z-Image) | [😄Link](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image) | Z-Image官方权重 |
|
||||
| Z-Image-Turbo | [🤗Link](https://huggingface.co/Tongyi-MAI/Z-Image-Turbo) | [😄Link](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo) | Z-Image-Turbo官方权重 |
|
||||
|
||||
## 9. Z-Image-Fun
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image-Fun-Controlnet-Union-2.1 | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1) | Z-Image 的 ControlNet 权重,支持 Canny、Depth、Pose、MLSD、Scribble和Gray 等多种控制条件。 |
|
||||
| Z-Image-Fun-Lora-Distill | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill) | 这是Z-Image的蒸馏LoRA,同时蒸馏了步数和CFG。该模型不需要CFG,推理仅使用8步。 |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union | - | [🤗链接](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union) | [😄链接](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union) | Z-Image-Turbo 的 ControlNet 权重,支持 Canny、Depth、Pose、MLSD 等多种控制条件。 |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union-2.1 | - | [🤗链接](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | [😄链接](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | Z-Image-Turbo 的 ControlNet 权重,相比第一版在更多层进行添加,也训练了更长时间,支持 Canny、Depth、Pose、MLSD 等多种控制条件。 |
|
||||
|
||||
## 10. Flux
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| FLUX.1-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.1-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev) | FLUX.1-dev官方权重 |
|
||||
| FLUX.2-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.2-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev) | FLUX.2-dev官方权重 |
|
||||
|
||||
## 11. Flux-Fun
|
||||
|
||||
| 名称 | 存储 | Hugging Face | 魔搭社区(ModelScope) | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Flux.2-dev-Fun-Controlnet-Union | - | [🤗链接](https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union) | [😄链接](https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union) | Flux.2-dev 的 ControlNet 权重,支持 Canny、Depth、Pose、MLSD 等多种控制条件。 |
|
||||
|
||||
## 12. HunyuanVideo
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| HunyuanVideo | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo) | - | HunyuanVideo-diffusers权重 |
|
||||
| HunyuanVideo-I2V | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo-I2V) | - | HunyuanVideo-I2V-diffusers权重 |
|
||||
|
||||
## 13. CogVideoX-Fun
|
||||
|
||||
V1.5:
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.5-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-5b-InP) | 官方的图生视频权重。支持多分辨率(512,768,1024)的视频预测,以85帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.5-Reward-LoRAs | - | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs) | 官方的奖励反向传播技术模型,优化CogVideoX-Fun-V1.5生成的视频,使其更好地符合人类偏好。 |
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
V1.1:
|
||||
通用控制视频 + 参考图像:
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.1-2b-InP | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-InP) | 官方的图生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.1-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP) | 官方的图生视频权重。添加了Noise,运动幅度相比于V1.0更大。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.1-2b-Pose | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Pose) | 官方的姿态控制生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.1-2b-Control | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Control) | 官方的控制生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练。支持不同的控制条件,如Canny、Depth、Pose、MLSD等 |
|
||||
| CogVideoX-Fun-V1.1-5b-Pose | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Pose) | 官方的姿态控制生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.1-5b-Control | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Control) | 官方的控制生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练。支持不同的控制条件,如Canny、Depth、Pose、MLSD等 |
|
||||
| CogVideoX-Fun-V1.1-Reward-LoRAs | - | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-Reward-LoRAs) | 官方的奖励反向传播技术模型,优化CogVideoX-Fun-V1.1生成的视频,使其更好地符合人类偏好。 |
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
参考图像
|
||||
</td>
|
||||
<td>
|
||||
控制视频
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-14B-Control
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-1.3B-Control
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
<details>
|
||||
<summary>(Obsolete) V1.0:</summary>
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-2b-InP) | 官方的图生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-5b-InP) | 官方的图生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
</details>
|
||||
通用控制视频(Canny、Pose、Depth 等)与轨迹控制:
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
# 五、参考文献
|
||||
本节列出[已支持的模型](#三已支持的模型)中各模型系列的官方仓库,以及本项目在实现与流程中参考的代码来源,感谢这些开源工作。
|
||||
|
||||
# 参考文献
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
|
||||
- Wan2.1: https://github.com/Wan-Video/Wan2.1/
|
||||
- Wan2.2: https://github.com/Wan-Video/Wan2.2/
|
||||
- Diffusers: https://github.com/huggingface/diffusers
|
||||
- HunyuanVideo: https://github.com/Tencent-Hunyuan/HunyuanVideo
|
||||
- HunyuanVideo-I2V: https://github.com/Tencent-Hunyuan/HunyuanVideo-I2V
|
||||
- MiniMax-H3: https://github.com/MiniMax-AI/MiniMax-H3
|
||||
- LTX-Video: https://github.com/Lightricks/LTX-Video
|
||||
- LTX-2: https://github.com/Lightricks/LTX-2
|
||||
- LongCat-Video: https://github.com/meituan-longcat/LongCat-Video
|
||||
- FantasyTalking: https://github.com/Fantasy-AMAP/fantasy-talking
|
||||
- InfiniteTalk: https://github.com/MeiGen-AI/InfiniteTalk
|
||||
- FlashHead: https://github.com/Soul-AILab/SoulX-FlashHead
|
||||
- MOVA: https://github.com/OpenMOSS/MOVA
|
||||
- LingBot-Video: https://github.com/Robbyant/lingbot-video
|
||||
- LingBot-World: https://github.com/Robbyant/lingbot-world
|
||||
- Phantom: https://github.com/Phantom-video/Phantom
|
||||
- Qwen-Image: https://github.com/QwenLM/Qwen-Image
|
||||
- Self-Forcing: https://github.com/guandeh17/Self-Forcing
|
||||
- Z-Image: https://github.com/Tongyi-MAI/Z-Image
|
||||
- Flux: https://github.com/black-forest-labs/flux
|
||||
- Flux2: https://github.com/black-forest-labs/flux2
|
||||
- HunyuanVideo: https://github.com/Tencent-Hunyuan/HunyuanVideo
|
||||
- ERNIE-Image: https://github.com/baidu/ernie-image
|
||||
- Lens: https://www.microsoft.com/en-us/research/publication/lens-rethinking-training-efficiency-for-foundational-text-to-image-models/
|
||||
- VACE: https://github.com/ali-vilab/VACE
|
||||
- CameraCtrl: https://github.com/hehao13/CameraCtrl
|
||||
- ComfyUI-CameraCtrl-Wrapper: https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper
|
||||
- DWPose: https://github.com/IDEA-Research/DWPose
|
||||
- MiDaS: https://github.com/isl-org/MiDaS
|
||||
- Self-Forcing: https://github.com/guandeh17/Self-Forcing
|
||||
- Causal-Forcing: https://github.com/thu-ml/Causal-Forcing
|
||||
- TurboDiffusion: https://github.com/thu-ml/TurboDiffusion
|
||||
- TAEHV: https://github.com/madebyollin/taehv
|
||||
- HPS v2: https://github.com/tgxs002/HPSv2
|
||||
- HPSv3: https://github.com/MizzenAI/HPSv3
|
||||
- MPS: https://github.com/Kwai-Kolors/MPS
|
||||
- Qwen2-VL: https://github.com/QwenLM/Qwen2-VL
|
||||
- AnimateDiff: https://github.com/guoyww/AnimateDiff
|
||||
- ComfyUI-KJNodes: https://github.com/kijai/ComfyUI-KJNodes
|
||||
- ComfyUI-EasyAnimateWrapper: https://github.com/kijai/ComfyUI-EasyAnimateWrapper
|
||||
- ComfyUI-CameraCtrl-Wrapper: https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper
|
||||
- CameraCtrl: https://github.com/hehao13/CameraCtrl
|
||||
- Diffusers: https://github.com/huggingface/diffusers
|
||||
|
||||
# 引用
|
||||
# 六、引用
|
||||
|
||||
如果您在研究或项目中使用了 VideoX-Fun,请按以下格式引用:
|
||||
|
||||
@@ -704,7 +503,7 @@ V1.1:
|
||||
}
|
||||
```
|
||||
|
||||
# 限制与风险
|
||||
# 七、限制与风险
|
||||
|
||||
- 生成的视频可能存在伪影或质量问题,尤其在复杂场景中。
|
||||
- 模型在处理精细细节、文字渲染或特定艺术风格时可能有困难。
|
||||
@@ -715,7 +514,7 @@ V1.1:
|
||||
|
||||
我们鼓励负责任地使用该技术,并建议在生产环境中实施安全措施。
|
||||
|
||||
# 许可证
|
||||
# 八、许可证
|
||||
本项目采用 [Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE).
|
||||
|
||||
CogVideoX-2B 模型 (包括其对应的Transformers模块,VAE模块) 根据 [Apache 2.0 协议](LICENSE) 许可证发布。
|
||||
|
||||
@@ -0,0 +1,9 @@
|
||||
# This file intentionally exists (empty) to make `midas` a regular package.
|
||||
#
|
||||
# Without it, `midas` is only a namespace-package portion, and Python's import
|
||||
# machinery lets ANY regular package named `midas` found elsewhere on sys.path
|
||||
# (e.g. comfyui_controlnet_aux's .../src/custom_controlnet_aux/midas/) win the
|
||||
# resolution, even though torch.hub.load inserts this midas_repo dir at
|
||||
# sys.path[0]. That collision produces:
|
||||
# ImportError: attempted relative import beyond top-level package
|
||||
# See https://github.com/aigc-apps/VideoX-Fun/issues/502
|
||||
@@ -120,6 +120,7 @@ class LoadCogVideoXFunModel:
|
||||
transformer = CogVideoXTransformer3DModel.from_pretrained(
|
||||
model_name,
|
||||
subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=torch.float8_e4m3fn if GPU_memory_mode == "model_cpu_offload_and_qfloat8" else weight_dtype,
|
||||
).to(weight_dtype)
|
||||
# Update pbar
|
||||
|
||||
@@ -0,0 +1,7 @@
|
||||
format: diffusers
|
||||
pipeline: minimax-h3
|
||||
transformer_additional_kwargs:
|
||||
control_blocks_places: [0, 5, 10, 15, 20, 25, 30, 35, 40, 45]
|
||||
control_in_dim: 49
|
||||
control_apply_audio: false
|
||||
inpaint_masked_pixel_mode: post_norm
|
||||
@@ -0,0 +1,52 @@
|
||||
format: civitai
|
||||
pipeline: Wan
|
||||
transformer_additional_kwargs:
|
||||
transformer_low_noise_model_subpath: ./low_noise_model
|
||||
transformer_high_noise_model_subpath: ./high_noise_model
|
||||
transformer_combination_type: "moe"
|
||||
boundary: 0.900
|
||||
dict_mapping:
|
||||
in_dim: in_channels
|
||||
dim: hidden_size
|
||||
|
||||
vae_kwargs:
|
||||
vae_type: "AutoencoderKLWan3_8"
|
||||
vae_subpath: Wan2.2_VAE.pth
|
||||
temporal_compression_ratio: 4
|
||||
spatial_compression_ratio: 16
|
||||
|
||||
latent_upsampler_kwargs:
|
||||
mid_channels: 512
|
||||
num_blocks_per_stage: 4
|
||||
dims: 3
|
||||
spatial_upsample: true
|
||||
temporal_upsample: false
|
||||
rational_spatial_scale: 1.5
|
||||
use_rational_resampler: true
|
||||
|
||||
text_encoder_kwargs:
|
||||
text_encoder_subpath: models_t5_umt5-xxl-enc-bf16.pth
|
||||
tokenizer_subpath: google/umt5-xxl
|
||||
text_length: 512
|
||||
vocab: 256384
|
||||
dim: 4096
|
||||
dim_attn: 4096
|
||||
dim_ffn: 10240
|
||||
num_heads: 64
|
||||
num_layers: 24
|
||||
num_buckets: 32
|
||||
shared_pos: False
|
||||
dropout: 0.0
|
||||
|
||||
scheduler_kwargs:
|
||||
scheduler_subpath: null
|
||||
num_train_timesteps: 1000
|
||||
shift: 5.0
|
||||
use_dynamic_shifting: false
|
||||
base_shift: 0.5
|
||||
max_shift: 1.15
|
||||
base_image_seq_len: 256
|
||||
max_image_seq_len: 4096
|
||||
|
||||
image_encoder_kwargs:
|
||||
image_encoder_subpath: models_clip_open-clip-xlm-roberta-large-vit-huge-14.pth
|
||||
@@ -0,0 +1,52 @@
|
||||
format: civitai
|
||||
pipeline: Wan
|
||||
transformer_additional_kwargs:
|
||||
transformer_low_noise_model_subpath: ./low_noise_model
|
||||
transformer_high_noise_model_subpath: ./high_noise_model
|
||||
transformer_combination_type: "moe"
|
||||
boundary: 0.875
|
||||
dict_mapping:
|
||||
in_dim: in_channels
|
||||
dim: hidden_size
|
||||
|
||||
vae_kwargs:
|
||||
vae_type: "AutoencoderKLWan3_8"
|
||||
vae_subpath: Wan2.2_VAE.pth
|
||||
temporal_compression_ratio: 4
|
||||
spatial_compression_ratio: 16
|
||||
|
||||
latent_upsampler_kwargs:
|
||||
mid_channels: 512
|
||||
num_blocks_per_stage: 4
|
||||
dims: 3
|
||||
spatial_upsample: true
|
||||
temporal_upsample: false
|
||||
rational_spatial_scale: 1.5
|
||||
use_rational_resampler: true
|
||||
|
||||
text_encoder_kwargs:
|
||||
text_encoder_subpath: models_t5_umt5-xxl-enc-bf16.pth
|
||||
tokenizer_subpath: google/umt5-xxl
|
||||
text_length: 512
|
||||
vocab: 256384
|
||||
dim: 4096
|
||||
dim_attn: 4096
|
||||
dim_ffn: 10240
|
||||
num_heads: 64
|
||||
num_layers: 24
|
||||
num_buckets: 32
|
||||
shared_pos: False
|
||||
dropout: 0.0
|
||||
|
||||
scheduler_kwargs:
|
||||
scheduler_subpath: null
|
||||
num_train_timesteps: 1000
|
||||
shift: 12.0
|
||||
use_dynamic_shifting: false
|
||||
base_shift: 0.5
|
||||
max_shift: 1.15
|
||||
base_image_seq_len: 256
|
||||
max_image_seq_len: 4096
|
||||
|
||||
image_encoder_kwargs:
|
||||
image_encoder_subpath: models_clip_open-clip-xlm-roberta-large-vit-huge-14.pth
|
||||
@@ -219,6 +219,7 @@ if partial_video_length is not None:
|
||||
additional_frames = transformer.config.patch_size_t - latent_frames % transformer.config.patch_size_t
|
||||
partial_video_length += additional_frames * vae.config.temporal_compression_ratio
|
||||
|
||||
validation_image = validation_image_start
|
||||
init_frames = 0
|
||||
last_frames = init_frames + partial_video_length
|
||||
while init_frames < video_length:
|
||||
|
||||
@@ -69,12 +69,12 @@ model_name = "models/Diffusion_Transformer/MiniMax-H3"
|
||||
# layers the control blocks attach to and `control_in_dim` the channels the control rows carry (49 for an
|
||||
# `--enable_inpaint` checkpoint, whose `control_proj_in` is widened with the mask channels). Leaving it None
|
||||
# builds the default 24-channel branch, which cannot load an inpaint checkpoint.
|
||||
config_path = "config/minimax_h3/minimax_h3_control.yaml"
|
||||
config_path = "config/minimax_h3/minimax_h3_control_inpaint_post_norm.yaml"
|
||||
|
||||
# Load pretrained model if need. The control branch is not part of the released MiniMax-H3 weights, so a base
|
||||
# `model_name` starts the side branch as an identity (`after_proj` is zero) and the c ontrol video has no effect;
|
||||
# point `transformer_path` at a control checkpoint trained by `scripts/minimax_h3_fun/train_control.py`.
|
||||
transformer_path = "models/Diffusion_Transformer/MiniMax-H3-Fun-Controlnet-Union/MiniMax-H3-Fun-Controlnet-Union.safetensors"
|
||||
transformer_path = "models/Diffusion_Transformer/MiniMax-H3-Fun-Controlnet-Union-2.0/MiniMax-H3-Fun-Controlnet-Union-2.0.safetensors"
|
||||
vae_path = None
|
||||
lora_path = None
|
||||
|
||||
@@ -101,7 +101,7 @@ control_video = "asset/pose.mp4"
|
||||
# the mask channels and the run degrades to pure generation; a mask-less checkpoint rejects them outright.
|
||||
inpaint_video = None
|
||||
inpaint_video_mask = None
|
||||
prompt = "视频中,一位年轻女性站在阳光洒满的沙滩上,背景是无垠碧蓝的大海与澄澈如洗的天空,构成一幅充满夏日度假氛围的画面。她身穿一件深海军蓝吊带泳衣,线条简约贴身,凸显健康匀称的身材曲线;外搭一条纯白色背带短裙,裙摆轻盈飘逸,随风微微扬起,增添了几分俏皮与少女感。她的长发柔顺披肩,发梢微卷,在阳光下泛着自然光泽,耳畔垂挂着一对小巧精致的珍珠吊坠耳环,为整体造型注入一丝温柔优雅的气息。她面带甜美笑容,嘴角上扬,露出整齐洁白的牙齿,眼神清澈明亮,直视镜头时流露出真诚与自信,仿佛在与观众分享此刻的快乐。起初,她双臂向两侧张开,手掌舒展,像是在拥抱整个大海与天空;随后手臂缓缓收回并向前挥动,动作节奏轻快而富有韵律,如同在跳舞或做简单的热身操,展现出轻松自在、无忧无虑的状态。她的腿部微微分开站立,姿态稳健又不失灵动,裙摆随着动作轻轻摇曳,与海风形成自然互动。远处海浪轻拍沙滩,发出柔和的“哗哗”声,虽无声但可想象其韵律,与她的动作相得益彰,营造出宁静而愉悦的听觉联想。"
|
||||
prompt = "视频中,一位年轻女性站在阳光洒满的沙滩上,背景是无垠碧蓝的大海与澄澈如洗的天空,构成一幅充满夏日度假氛围的画面。她身穿一件深海军蓝吊带泳衣,线条简约贴身,凸显健康匀称的身材曲线;外搭一条纯白色背带短裙,裙摆轻盈飘逸,随风微微扬起,增添了几分俏皮与少女感。她的长发柔顺披肩,发梢微卷,在阳光下泛着自然光泽,耳畔垂挂着一对小巧精致的珍珠吊坠耳环,为整体造型注入一丝温柔优雅的气息。她面带甜美笑容,嘴角上扬,露出整齐洁白的牙齿,眼神清澈明亮,直视镜头时流露出真诚与自信,仿佛在与观众分享此刻的快乐。"
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
seed = 43
|
||||
# Number of denoising steps, i.e. of model evaluations: num_inference_steps = 40 runs 40 of them.
|
||||
|
||||
@@ -0,0 +1,364 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLMiniMaxH3,
|
||||
AutoencoderKLMiniMaxH3Audio,
|
||||
MiniMaxH3ControlTransformer3DModel,
|
||||
Qwen2TokenizerFast,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor)
|
||||
from videox_fun.pipeline import MiniMaxH3ControlPipeline
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (get_video_to_video_latent,
|
||||
save_videos_with_audio_grid)
|
||||
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "model_group_offload"
|
||||
# Multi GPUs config
|
||||
# Please ensure that the product of ulysses_degree and ring_degree equals the number of GPUs used.
|
||||
# For example, if you are using 8 GPUs, you can set ulysses_degree = 2 and ring_degree = 4.
|
||||
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
|
||||
# Multi-GPU runs through the xfuser sequence-parallel path and must be launched with torchrun, e.g.
|
||||
# `torchrun --nproc_per_node=2 examples/minimax_h3_fun/predict_v2v_control.py` for ulysses_degree=2, ring_degree=1.
|
||||
# It is incompatible with the *cpu_offload* memory modes (accelerate offload hooks own a single device);
|
||||
# use model_full_load / model_full_load_and_qfloat8 there, with fsdp_dit to save memory.
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus. The Qwen3-VL conditioner is ~62 GB, so with fsdp_dit alone every
|
||||
# rank still replicates it; fsdp_text_encoder shards it too. Note it must wrap the inner `text_encoder.model`
|
||||
# (Qwen3VLModel): encode_prompt calls that submodule directly, so a wrap on the top-level module would never fire.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = True
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/MiniMax-H3"
|
||||
# Control branch layout, must match the yaml `train_control.py` ran with: `control_blocks_places` selects the
|
||||
# layers the control blocks attach to and `control_in_dim` the channels the control rows carry (49 for an
|
||||
# `--enable_inpaint` checkpoint, whose `control_proj_in` is widened with the mask channels). Leaving it None
|
||||
# builds the default 24-channel branch, which cannot load an inpaint checkpoint.
|
||||
config_path = "config/minimax_h3/minimax_h3_control_inpaint_post_norm.yaml"
|
||||
|
||||
# Load pretrained model if need. The control branch is not part of the released MiniMax-H3 weights, so a base
|
||||
# `model_name` starts the side branch as an identity (`after_proj` is zero) and the c ontrol video has no effect;
|
||||
# point `transformer_path` at a control checkpoint trained by `scripts/minimax_h3_fun/train_control.py`.
|
||||
transformer_path = "models/Diffusion_Transformer/MiniMax-H3-Fun-Controlnet-Union-2.0/MiniMax-H3-Fun-Controlnet-Union-2.0.safetensors"
|
||||
vae_path = None
|
||||
lora_path = None
|
||||
|
||||
# Other params
|
||||
# MiniMax-H3 generates at a fixed 24 fps, only accepts multiples of 32 as height / width, and the generation
|
||||
# follows the control video's actual length — snapped down to the largest 17 * n + 5 the video VAE can decode so
|
||||
# a short control video is never padded (the duration has to stay under 15 seconds), capped by video_length.
|
||||
# Control inference fits the control video onto this canvas with the training's resize + crop geometry, so
|
||||
# sample_size must be set (it cannot be None).
|
||||
sample_size = [704, 1280]
|
||||
video_length = 124
|
||||
fps = 24
|
||||
# Scale applied to every control skip before it is added to the main branch. 0.0 switches the control branch off,
|
||||
# values below 1.0 weaken the guidance of the control video.
|
||||
control_context_scale = 1.00
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# Path of the control (e.g. pose) video; leaving it None zeroes the control channels of the side branch. With
|
||||
# inpaint inputs given the mask then guides the run on its own (the layout training reaches when it drops the
|
||||
# control rows); without them the run degrades to plain base-pipeline generation at `video_length` frames.
|
||||
control_video = None
|
||||
# Inpaint inputs, only read by checkpoints trained with `--enable_inpaint` (control_in_dim widened, e.g. 49):
|
||||
# `inpaint_video` is the source video behind the mask and `inpaint_video_mask` marks the regions to regenerate
|
||||
# (white = repaint, black = keep). With an inpaint checkpoint but no inpaint inputs given, the pipeline zero-pads
|
||||
# the mask channels and the run degrades to pure generation; a mask-less checkpoint rejects them outright.
|
||||
inpaint_video = "asset/inpaint_video.mp4"
|
||||
inpaint_video_mask = "asset/inpaint_video_mask.mp4"
|
||||
prompt = "一只狗在沙发上摇头"
|
||||
seed = 43
|
||||
# Number of denoising steps, i.e. of model evaluations: num_inference_steps = 40 runs 40 of them.
|
||||
num_inference_steps = 40
|
||||
# The released checkpoint is guidance-distilled: leave guidance_scale at 1 to run one forward pass per step
|
||||
# with no CFG — the distill checkpoints of train_control_distill.py already bake the teacher's CFG target into
|
||||
# the weights, so any value above 1 applies guidance twice and degrades the output. A value above 1 enables
|
||||
# classifier-free guidance with a negative_prompt, running two passes.
|
||||
guidance_scale = 1.0
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
# The exponential sigma shifts of the two schedules. None keeps the ones of the checkpoint (12.0 video, 3.0 audio).
|
||||
flow_shift = None
|
||||
audio_flow_shift = None
|
||||
lora_weight = 0.55
|
||||
save_path = "samples/minimax-h3-videos-v2v-control"
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
|
||||
# The yaml pins the control branch layout exactly as in training (scripts/minimax_h3_fun/train_control.py), where
|
||||
# `transformer_additional_kwargs` is spread into `from_pretrained` the same way.
|
||||
transformer_load_kwargs = {}
|
||||
if config_path is not None:
|
||||
from omegaconf import OmegaConf
|
||||
config = OmegaConf.load(config_path)
|
||||
transformer_load_kwargs.update(
|
||||
OmegaConf.to_container(config["transformer_additional_kwargs"], resolve=True)
|
||||
)
|
||||
|
||||
# `model_name` may point either at a converted diffusers layout or at an *original* MiniMax-H3 partition (e.g.
|
||||
# `MiniMax-H3/FL2VA`); the original shards are converted on the fly while loading, no intermediate copy on disk.
|
||||
# Transformer. `from_pretrained` fills the control branch the released checkpoint does not carry: every control
|
||||
# block is initialised from the main block it is attached to and `control_proj_in` from `proj_in`, with
|
||||
# before_proj / after_proj zeroed, so a freshly loaded model is numerically identical to the base MiniMax-H3 model.
|
||||
transformer = MiniMaxH3ControlTransformer3DModel.from_pretrained(
|
||||
model_name,
|
||||
subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
**transformer_load_kwargs,
|
||||
)
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Video VAE. The released weights are float32 and the decode runs under float16 autocast, so the VAE is not
|
||||
# downcast even when the rest of the pipeline is bfloat16.
|
||||
vae = AutoencoderKLMiniMaxH3.from_pretrained(
|
||||
model_name,
|
||||
subfolder="vae",
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Audio VAE, waveform in / waveform out: MiniMax-H3 has no separate vocoder.
|
||||
audio_vae = AutoencoderKLMiniMaxH3Audio.from_pretrained(
|
||||
model_name,
|
||||
subfolder="audio_vae",
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
|
||||
# Get Tokenizer and Processor
|
||||
tokenizer = Qwen2TokenizerFast.from_pretrained(os.path.join(model_name, "tokenizer"))
|
||||
processor = Qwen3VLProcessor.from_pretrained(os.path.join(model_name, "processor"))
|
||||
|
||||
# Get Text encoder. MiniMax-H3 reads the unnormalized hidden state after the 50th decoder layer of Qwen3-VL.
|
||||
text_encoder = Qwen3VLForConditionalGeneration.from_pretrained(
|
||||
os.path.join(model_name, "text_encoder"),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Schedulers. MiniMax-H3 steps the video and the audio latents down two schedules inside one transformer call.
|
||||
scheduler = MiniMaxH3Scheduler.from_pretrained(model_name, subfolder="scheduler")
|
||||
audio_scheduler = MiniMaxH3Scheduler.from_pretrained(model_name, subfolder="audio_scheduler")
|
||||
|
||||
pipeline = MiniMaxH3ControlPipeline(
|
||||
vae=vae,
|
||||
audio_vae=audio_vae,
|
||||
text_encoder=text_encoder,
|
||||
tokenizer=tokenizer,
|
||||
processor=processor,
|
||||
transformer=transformer,
|
||||
scheduler=scheduler,
|
||||
audio_scheduler=audio_scheduler,
|
||||
)
|
||||
|
||||
# The float32 modules of the mixed-precision checkpoint stay untouched by the float8 quantization. The `proj_in`
|
||||
# entry also covers the control patch projection `control_proj_in`, which shares the video patch projection's dtype.
|
||||
fp8_exclude_module_name = [
|
||||
"proj_in", "audio_proj_in", "context_embedder", "time_embedder", "time_proj",
|
||||
"token_refiner", "norm_out", "proj_out", "audio_proj_out",
|
||||
]
|
||||
use_qfloat8 = "qfloat8" in GPU_memory_mode
|
||||
if use_qfloat8:
|
||||
# Scale-aware fp8 must run before the FSDP wrapping below so the flat buffers hold the fp8 values.
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=fp8_exclude_module_name, device=device)
|
||||
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
# The mixed-precision checkpoint pins the patch embedders / timestep MLP / output heads to float32;
|
||||
# FSDP keeps them replicated via ignored_states so the flat buffers stay uniform-dtype.
|
||||
#
|
||||
# Root cause of the temporal flicker, verified by per-step / per-block instrumentation: with
|
||||
# `MixedPrecision(param_dtype=...)` the root FSDP unit applies `cast_root_forward_inputs` (default
|
||||
# True), so the whole root forward runs in `param_dtype`. That casts the root forward inputs — the
|
||||
# sinusoidal timestep embedding, the packed latents, the context — to bfloat16 and forces the fp32-
|
||||
# pinned heads (proj_in / time_embedder / audio_proj_in) to compute on coarsely rounded inputs in
|
||||
# bfloat16 instead of their native fp32; the deviation compounds over the sampling steps and flips
|
||||
# trajectories that sit on the numerical-stability edge into coherent flicker at fixed latent-time
|
||||
# positions, seed-independently.
|
||||
# Sharding with `param_dtype=None` + `cast_dtype=False` casts nothing (no MixedPrecision compute
|
||||
# dtype, no root input cast), keeps the native fp32 hidden path and matches the non-FSDP numerics.
|
||||
fp32_modules = [m for m in transformer.modules()
|
||||
if any(p.dtype == torch.float32 for p in m.parameters(recurse=False))]
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=None, cast_dtype=False,
|
||||
module_to_wrapper=list(transformer.transformer_blocks) + list(transformer.control_blocks),
|
||||
ignored_modules=fp32_modules)
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype,
|
||||
module_to_wrapper=list(text_encoder.model.language_model.layers))
|
||||
pipeline.text_encoder.model = shard_fn(pipeline.text_encoder.model)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.transformer_blocks)):
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
def snap_num_frames(actual_num_frames, max_num_frames):
|
||||
"""
|
||||
Pick the generation length from the control video instead of padding a short one: the largest `17 * n + 5`
|
||||
the video VAE can decode that does not exceed the frames actually read (capped by `max_num_frames`), snapping
|
||||
down so no tail frame is ever repeated. A control video below 5 frames is raised to 5, the smallest count
|
||||
the video VAE can encode.
|
||||
"""
|
||||
num_frames = min(actual_num_frames, max_num_frames)
|
||||
num_frames = (num_frames - 5) // 17 * 17 + 5
|
||||
return max(num_frames, 5)
|
||||
|
||||
with torch.no_grad():
|
||||
control_video, _, _, _ = get_video_to_video_latent(control_video, video_length=video_length, sample_size=sample_size, fps=fps, ref_image=None, keep_aspect_ratio=True)
|
||||
|
||||
# Generate at the control video's actual length, never padding; only control videos below the 5 frames the
|
||||
# video VAE can encode are raised to 5. Without a control video the request keeps `video_length`, which the
|
||||
# pipeline snaps up to the next 17 * n + 5 itself (control branch off = plain base-pipeline generation).
|
||||
if control_video is None:
|
||||
num_frames = video_length
|
||||
print(f"[{os.environ.get('RANK', '0')}] no control video given, "
|
||||
+ (f"running inpaint alone at {num_frames} frames" if inpaint_video is not None
|
||||
else f"generating {num_frames} frames without the control branch"), flush=True)
|
||||
else:
|
||||
num_frames = snap_num_frames(control_video.shape[2], video_length)
|
||||
if num_frames != video_length:
|
||||
print(f"[{os.environ.get('RANK', '0')}] control video holds {control_video.shape[2]} frames, generating "
|
||||
f"{num_frames} instead of {video_length}", flush=True)
|
||||
|
||||
mask_video = None
|
||||
if inpaint_video is not None:
|
||||
if inpaint_video_mask is None:
|
||||
raise ValueError("inpaint_video_mask is required when inpaint_video is provided")
|
||||
inpaint_video, _, _, _ = get_video_to_video_latent(inpaint_video, video_length=video_length, sample_size=sample_size, fps=fps, ref_image=None, keep_aspect_ratio=True)
|
||||
inpaint_video_mask, _, _, _ = get_video_to_video_latent(inpaint_video_mask, video_length=video_length, sample_size=sample_size, fps=fps, ref_image=None, keep_aspect_ratio=True)
|
||||
# Binarize the grayscale mask onto one channel: 1 marks the regions to regenerate, mirroring the training
|
||||
# `get_random_mask` convention the visibility map `1 - mask` is built from.
|
||||
mask_video = (inpaint_video_mask[:, :1] > 0.5).to(inpaint_video_mask.dtype)
|
||||
|
||||
output = pipeline(
|
||||
prompt=prompt,
|
||||
control_video=control_video,
|
||||
control_context_scale=control_context_scale,
|
||||
mask_video=mask_video,
|
||||
inpaint_video=inpaint_video,
|
||||
height=None if sample_size is None else sample_size[0],
|
||||
width=None if sample_size is None else sample_size[1],
|
||||
num_frames=num_frames,
|
||||
num_inference_steps=num_inference_steps,
|
||||
flow_shift=flow_shift,
|
||||
audio_flow_shift=audio_flow_shift,
|
||||
guidance_scale=guidance_scale,
|
||||
negative_prompt=negative_prompt,
|
||||
generator=generator,
|
||||
output_type="pt",
|
||||
)
|
||||
print(f"[{os.environ.get('RANK', '0')}] generation done, decoding", flush=True)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
sample = output.videos
|
||||
audio = output.audio
|
||||
audio_sample_rate = output.sampling_rate
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_with_audio_grid(sample, audio, video_path, fps=fps, audio_sample_rate=audio_sample_rate)
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
# Keep every rank alive until the saving rank finishes; an early exit of one rank makes the elastic launcher
|
||||
# terminate the others.
|
||||
dist.barrier()
|
||||
else:
|
||||
save_results()
|
||||
@@ -0,0 +1,223 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import torch
|
||||
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLQwenImage21,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor, QwenImage21Transformer2DModel)
|
||||
from videox_fun.pipeline import QwenImage21Pipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "model_group_offload"
|
||||
# Multi GPUs config
|
||||
# Qwen-Image 2.1 uses a block-causal single-stream transformer with a prefix KV cache, which is not
|
||||
# compatible with the sequence-parallel attention used by the other families. Please run it on a single
|
||||
# GPU (ulysses_degree = 1 and ring_degree = 1).
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = False
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with the fsdp_dit and sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
|
||||
# Choose the sampler. Qwen-Image 2.1 is a flow-matching model sampled with the Euler discrete scheduler.
|
||||
sampler_name = "Flow"
|
||||
|
||||
# Load pretrained model if need
|
||||
transformer_path = None
|
||||
vae_path = None
|
||||
lora_path = None
|
||||
|
||||
# Other params
|
||||
# sample_size is the output canvas in pixels as [height, width]; the pipeline rounds it down to a
|
||||
# multiple of 32. Leave it as None to fall back to the pipeline's default square resolution.
|
||||
sample_size = [1024, 1024]
|
||||
# Cache the text and condition-image keys/values after the first denoising step. Valid because the
|
||||
# transformer modulates those tokens from t = 0, making their activations step-independent.
|
||||
use_kv_cache = True
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# Please use as detailed a prompt as possible to describe the object that needs to be generated.
|
||||
prompts = ["a young girl with flowing long hair, wearing a white halter dress and smiling sweetly. The background features a blue seaside where seagulls fly freely."]
|
||||
negative_prompt = " "
|
||||
guidance_scale = 1.0
|
||||
seed = 43
|
||||
num_inference_steps = 40
|
||||
lora_weight = 0.55
|
||||
save_path = "samples/qwenimage21-t2i"
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
|
||||
transformer = QwenImage21Transformer2DModel.from_pretrained(
|
||||
model_name,
|
||||
subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
).to(weight_dtype)
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Vae
|
||||
vae = AutoencoderKLQwenImage21.from_pretrained(
|
||||
model_name,
|
||||
subfolder="vae"
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get processor and text_encoder. Qwen-Image 2.1 encodes the prompt (and any condition images) with a
|
||||
# Qwen3-VL model, so a processor replaces the plain tokenizer used by the earlier Qwen-Image families.
|
||||
processor = Qwen3VLProcessor.from_pretrained(
|
||||
model_name, subfolder="processor"
|
||||
)
|
||||
text_encoder = Qwen3VLForConditionalGeneration.from_pretrained(
|
||||
model_name, subfolder="text_encoder", torch_dtype=weight_dtype
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
}[sampler_name]
|
||||
scheduler = Chosen_Scheduler.from_pretrained(
|
||||
model_name,
|
||||
subfolder="scheduler"
|
||||
)
|
||||
|
||||
pipeline = QwenImage21Pipeline(
|
||||
vae=vae,
|
||||
text_encoder=text_encoder,
|
||||
processor=processor,
|
||||
transformer=transformer,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=list(transformer.transformer_blocks))
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
from functools import partial
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype, module_to_wrapper=text_encoder.model.language_model.layers)
|
||||
text_encoder = shard_fn(text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.transformer_blocks)):
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "time_text_embed", "modulation"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["img_in", "txt_in", "time_text_embed", "modulation"], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
for prompt in prompts:
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
with torch.no_grad():
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
negative_prompt = negative_prompt,
|
||||
height = sample_size[0] if sample_size is not None else None,
|
||||
width = sample_size[1] if sample_size is not None else None,
|
||||
generator = generator,
|
||||
true_cfg_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
use_kv_cache = use_kv_cache,
|
||||
).images
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
image_path = os.path.join(save_path, prefix + ".png")
|
||||
image = sample[0]
|
||||
image.save(image_path)
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
else:
|
||||
save_results()
|
||||
@@ -0,0 +1,612 @@
|
||||
import json
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchaudio
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices
|
||||
from videox_fun.models import (AutoencoderKLMiniMaxH3,
|
||||
AutoencoderKLMiniMaxH3Audio,
|
||||
MiniMaxH3Transformer3DModel, Qwen2TokenizerFast,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor)
|
||||
from videox_fun.pipeline import MiniMaxH3Pipeline
|
||||
from videox_fun.pipeline.pipeline_minimax_h3 import (MINIMAX_H3_AUDIO_TAG,
|
||||
MINIMAX_H3_TEXT_TAG,
|
||||
_spatial_position_grid)
|
||||
from videox_fun.pipeline.pipeline_taomate_h3 import (
|
||||
TAOMATE_H3_AUDIO_LATENT_CHANNELS, TAOMATE_H3_AUDIO_SIGMA_SHIFT,
|
||||
TAOMATE_H3_DISTILLED_STATE_INDICES, TAOMATE_H3_REQUEST_AUDIO_LATENTS,
|
||||
TAOMATE_H3_REQUEST_VIDEO_LATENTS, TAOMATE_H3_ROLLOVER_REFERENCE_LATENTS,
|
||||
TAOMATE_H3_SUPPORTED_SHORT_EDGES, TAOMATE_H3_TEACHER_STATE_NUMBERS,
|
||||
TAOMATE_H3_VIDEO_SIGMA_SHIFT, taomate_h3_canonical_continuation_plan,
|
||||
taomate_h3_direct_5s_plan, taomate_h3_select_time_shift_sigmas,
|
||||
taomate_h3_teacher_geometry)
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_cpu_offload, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
# The transformer alone is 61.7 GB in bfloat16 and the Qwen3-VL conditioner another 62.1 GB, so a single 80 GB
|
||||
# card needs an offload mode. The float8-quantizing modes are deliberately absent: the audio path is the Base10
|
||||
# teacher's, running the *base* weights exactly as released (no LoRA — the TaoMate-H3 adapter only steers the
|
||||
# video), and the artifact records `base_precision=bf16`.
|
||||
GPU_memory_mode = "model_cpu_offload"
|
||||
# Multi GPUs config. The audio-only loop drives the transformer directly and runs one request's whole packed
|
||||
# sequence on one GPU, so keep ulysses_degree = ring_degree = 1.
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/MiniMax-H3"
|
||||
|
||||
# Other params
|
||||
# The canvas: the short edge must be 480, 768 or 1088 and both edges 32-aligned (480x864 is the resolution
|
||||
# the official TaoMate-H3 demo ships). The teacher artifact is bound to this geometry, and the audio noise
|
||||
# identity depends on it too (the discarded video-noise draw is canvas-shaped).
|
||||
sample_size = [864, 480]
|
||||
# How many 5-second requests to generate: the first one runs the direct 124-frame plan, every following one
|
||||
# the canonical continuation spliced behind its predecessor — it denoises the previous request's clean tail
|
||||
# (`TAOMATE_H3_ROLLOVER_REFERENCE_LATENTS` latents per channel, read-only) together with its own fresh noise.
|
||||
request_count = 2
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# The prompt the default Base10 teacher artifact (`samples/taomate_h3_teacher/00000000`) was generated for —
|
||||
# `Self-Forcing/prompts/self_forcing_all_prompts.json` entry 0. A list gives one prompt per stream request
|
||||
# (the official `--prompt-json` shape) and the artifact then carries exactly those prompts; a string covers
|
||||
# the whole timeline.
|
||||
prompt = (
|
||||
"A stylish woman strolls down a bustling Tokyo street, the warm glow of neon lights and animated city "
|
||||
"signs casting vibrant reflections. She wears a sleek black leather jacket paired with a flowing red "
|
||||
"dress and black boots, her black purse slung over her shoulder. Sunglasses perched on her nose and a "
|
||||
"bold red lipstick add to her confident, casual demeanor. The street is damp and reflective, creating a "
|
||||
"mirror-like effect that enhances the colorful lights and shadows. Pedestrians move about, adding to the "
|
||||
"lively atmosphere. The scene is captured in a dynamic medium shot with the woman walking slightly to "
|
||||
"one side, highlighting her graceful strides."
|
||||
)
|
||||
# The authored seed. Request j draws its audio noise from seed + j — the streaming runtime replays the same
|
||||
# sequence from the artifact's `audio_noise_seed_sequence`.
|
||||
seed = 43
|
||||
# The offline Base10 audio-teacher artifact directory to write: `predict_t2av_streaming.py` reads this
|
||||
# very value back through its own `audio_teacher_dir`, so keep the two identical. The artifact
|
||||
# (`complete.json` + `request_XX.pt`) holds the clean audio rows after denoising steps 3, 6 and 9 and
|
||||
# is bound to the prompt(s), seed and canvas above. Set to None to only save the wav.
|
||||
audio_teacher_dir = "samples/taomate_h3_teacher/00000000"
|
||||
save_path = "samples/taomate-h3-audios-t2a"
|
||||
|
||||
# `sample_size` must fit the streaming canvas contract, and the artifact is only ever `base_precision=bf16`.
|
||||
if min(sample_size) not in TAOMATE_H3_SUPPORTED_SHORT_EDGES or sample_size[0] % 32 or sample_size[1] % 32:
|
||||
raise ValueError(
|
||||
f"`sample_size` {sample_size} must use a 480-, 768- or 1088-pixel short edge and be 32-pixel "
|
||||
"aligned, matching the streaming canvas contract (e.g. [864, 480])."
|
||||
)
|
||||
if request_count < 1:
|
||||
raise ValueError(f"`request_count` must be positive, got {request_count}.")
|
||||
if audio_teacher_dir is not None and weight_dtype != torch.bfloat16:
|
||||
raise ValueError(
|
||||
"the Base10 teacher artifact records `base_precision=bf16`; set `audio_teacher_dir = None` to "
|
||||
"only save the wav, or run with `weight_dtype = torch.bfloat16`."
|
||||
)
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
|
||||
# `model_name` may point either at a converted diffusers layout or at an *original* MiniMax-H3 partition (e.g.
|
||||
# `MiniMax-H3/FL2VA`); the original shards are converted on the fly while loading, no intermediate copy on disk.
|
||||
# Transformer
|
||||
transformer = MiniMaxH3Transformer3DModel.from_pretrained(
|
||||
model_name,
|
||||
subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
|
||||
# Video VAE. The released weights are float32 and the decode runs under float16 autocast, so the VAE is not
|
||||
# downcast even when the rest of the pipeline is bfloat16 (this is also how the training scripts load it).
|
||||
# The audio-only path never decodes video — the container holds it only to satisfy `MiniMaxH3Pipeline`.
|
||||
vae = AutoencoderKLMiniMaxH3.from_pretrained(
|
||||
model_name,
|
||||
subfolder="vae",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
|
||||
# Audio VAE, waveform in / waveform out: MiniMax-H3 has no separate vocoder. Float32 as released, like the video VAE.
|
||||
audio_vae = AutoencoderKLMiniMaxH3Audio.from_pretrained(
|
||||
model_name,
|
||||
subfolder="audio_vae",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
|
||||
# Get Tokenizer and Processor
|
||||
tokenizer = Qwen2TokenizerFast.from_pretrained(os.path.join(model_name, "tokenizer"))
|
||||
processor = Qwen3VLProcessor.from_pretrained(os.path.join(model_name, "processor"))
|
||||
|
||||
# Get Text encoder. MiniMax-H3 reads the unnormalized hidden state after the 50th decoder layer of Qwen3-VL.
|
||||
text_encoder = Qwen3VLForConditionalGeneration.from_pretrained(
|
||||
os.path.join(model_name, "text_encoder"),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Schedulers. The 10-step Base schedule is rebuilt from the checkpoint's own sigma shifts
|
||||
# (`taomate_h3_select_time_shift_sigmas`), so the checkpoint schedules only seed the class.
|
||||
scheduler = MiniMaxH3Scheduler.from_pretrained(model_name, subfolder="scheduler")
|
||||
audio_scheduler = MiniMaxH3Scheduler.from_pretrained(model_name, subfolder="audio_scheduler")
|
||||
|
||||
pipeline = MiniMaxH3Pipeline(
|
||||
vae=vae,
|
||||
audio_vae=audio_vae,
|
||||
text_encoder=text_encoder,
|
||||
tokenizer=tokenizer,
|
||||
processor=processor,
|
||||
transformer=transformer,
|
||||
scheduler=scheduler,
|
||||
audio_scheduler=audio_scheduler,
|
||||
)
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.transformer_blocks)):
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load":
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
raise ValueError(
|
||||
f"`GPU_memory_mode` must be one of ['model_full_load', 'model_cpu_offload', 'model_group_offload', "
|
||||
f"'sequential_cpu_offload'], got {GPU_memory_mode}."
|
||||
)
|
||||
|
||||
|
||||
def official_audio_noise(*, video_latent_t, video_latent_h, video_latent_w, audio_latent_t, seed):
|
||||
"""The exact initial audio noise of one request, the offline teacher's arithmetic.
|
||||
|
||||
H3 draws full-AV video noise before audio. The audio-only path discards those values, but
|
||||
advancing this exact CPU generator is part of the audio identity, and the streaming student
|
||||
reuses the very same rows as its initial audio noise. `24` is MiniMax-H3's video VAE latent
|
||||
channel count; the canvas enters the identity through this draw's shape.
|
||||
"""
|
||||
generator = torch.Generator(device="cpu").manual_seed(seed)
|
||||
torch.randn(
|
||||
1, 24, video_latent_t, video_latent_h, video_latent_w,
|
||||
generator=generator, dtype=torch.float32, device="cpu",
|
||||
)
|
||||
return torch.randn(
|
||||
2 * audio_latent_t, TAOMATE_H3_AUDIO_LATENT_CHANNELS,
|
||||
generator=generator, dtype=torch.float32, device="cpu",
|
||||
)
|
||||
|
||||
|
||||
def audio_only_packed_layout(
|
||||
text_len, ref_audio_t, audio_t, latent_h, latent_w, *, reference_time_start, target_time_start
|
||||
):
|
||||
"""The audio-only packed sequence `[text | (reference audio |) target audio]`, the offline teacher's
|
||||
arithmetic.
|
||||
|
||||
Mirrors the official `minimax_h3_audio_only_packed_sequence` and
|
||||
`minimax_h3_audio_only_frozen_prefix_packed_sequence` builders, minus the 64-row attention
|
||||
padding (a single-GPU sequence needs no alignment). Rows order their time axis per channel
|
||||
block — `[ch0 rows; ch1 rows]` — matching the audio-row storage order.
|
||||
"""
|
||||
patch = 2
|
||||
ref_rows = ref_audio_t * 2
|
||||
target_rows = audio_t * 2
|
||||
total_rows = ref_rows + target_rows
|
||||
sequence_length = text_len + total_rows
|
||||
|
||||
sqrt_area = np.sqrt(latent_h * latent_w)
|
||||
width_grid = _spatial_position_grid(latent_w, patch, sqrt_area)
|
||||
|
||||
grid = torch.zeros(sequence_length, 3, dtype=torch.float64)
|
||||
grid[:text_len, 0] = torch.arange(text_len, dtype=torch.float64)
|
||||
row_index = text_len
|
||||
for temporal_rows, time_start in ((ref_audio_t, reference_time_start), (audio_t, target_time_start)):
|
||||
if temporal_rows <= 0:
|
||||
continue
|
||||
times = (float(time_start) + torch.arange(temporal_rows, dtype=torch.float64)).repeat(2)
|
||||
grid[row_index : row_index + 2 * temporal_rows, 0] = times
|
||||
grid[row_index : row_index + temporal_rows, 2] = float(width_grid[0])
|
||||
grid[row_index + temporal_rows : row_index + 2 * temporal_rows, 2] = float(width_grid[-1])
|
||||
row_index += 2 * temporal_rows
|
||||
|
||||
token_tags = torch.full((sequence_length,), -1, dtype=torch.long)
|
||||
token_tags[:text_len] = MINIMAX_H3_TEXT_TAG
|
||||
token_tags[text_len:] = MINIMAX_H3_AUDIO_TAG
|
||||
|
||||
return {
|
||||
"sequence_length": sequence_length,
|
||||
"position_ids": grid,
|
||||
"token_tags": token_tags,
|
||||
"text_indices": torch.arange(text_len),
|
||||
"audio_indices": torch.arange(text_len, sequence_length),
|
||||
"ref_rows": ref_rows,
|
||||
"target_rows": target_rows,
|
||||
}
|
||||
|
||||
|
||||
def audio_only_step_timesteps(t_video, t_audio, *, has_reference):
|
||||
"""The `(timestep, timestep_indices)` pair of one audio-only forward, the offline teacher's arithmetic.
|
||||
|
||||
Text rows ride the video clock, target audio rows the audio clock, and the frozen reference
|
||||
rows stay pinned at `1.0` — the timestep of a clean row (`t = 1 - sigma` with `sigma = 0`),
|
||||
exactly as the reference audio in the student's layouts.
|
||||
"""
|
||||
candidates = [float(t_video), float(t_audio)]
|
||||
if has_reference:
|
||||
candidates.append(1.0)
|
||||
unique_timesteps, slot_to_unique = torch.unique(
|
||||
torch.tensor(candidates, dtype=torch.float32), sorted=True, return_inverse=True
|
||||
)
|
||||
text_slot = int(slot_to_unique[0])
|
||||
target_slot = int(slot_to_unique[1])
|
||||
reference_slot = int(slot_to_unique[2]) if has_reference else None
|
||||
|
||||
def expand(text_rows, ref_rows, total_rows):
|
||||
indices = torch.empty(total_rows, dtype=torch.long)
|
||||
indices[:text_rows] = text_slot
|
||||
if ref_rows:
|
||||
indices[text_rows : text_rows + ref_rows] = reference_slot
|
||||
indices[text_rows + ref_rows :] = target_slot
|
||||
return indices
|
||||
|
||||
return unique_timesteps, expand
|
||||
|
||||
|
||||
_OFFLOAD_MODES = ("model_cpu_offload", "model_group_offload", "sequential_cpu_offload")
|
||||
|
||||
|
||||
def _park_on_cpu(module):
|
||||
"""Send a component back to the CPU under an offload mode, so the next component fits.
|
||||
|
||||
`model_cpu_offload` only orchestrates component transfers inside `pipeline.__call__`; this
|
||||
script drives the components directly, so each pass parks what it just used. Under
|
||||
`model_full_load` nothing is parked.
|
||||
"""
|
||||
if GPU_memory_mode not in _OFFLOAD_MODES:
|
||||
return
|
||||
if next(module.parameters()).device.type != "cpu":
|
||||
module.to("cpu")
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
|
||||
def generate_audio_track(pipeline, *, prompt, seed, request_count, height, width, device):
|
||||
"""Denoise `request_count` 5-second audio-only requests and return their clean packed rows.
|
||||
|
||||
Returns `(clean_rows, request_records)`: `clean_rows` is `(2 * total_audio_latents,
|
||||
audio_latent_channels)` float32 on the CPU — the exact rows `MiniMaxH3StreamingPipeline`
|
||||
publishes (it hard-asserts they equal the Base10 teacher's final clean state), before that
|
||||
pipeline's one-shot VAE decode — and `request_records` carries one record per request with its
|
||||
captured 3/6/9 milestones plus the metadata `write_teacher_artifact` needs.
|
||||
"""
|
||||
if isinstance(prompt, str):
|
||||
prompts = [prompt] * request_count
|
||||
else:
|
||||
prompts = list(prompt)
|
||||
if len(prompts) != request_count:
|
||||
raise ValueError(
|
||||
f"`prompt` lists {len(prompts)} entries but `request_count` is {request_count}: a list gives "
|
||||
"one prompt per stream request."
|
||||
)
|
||||
|
||||
latent_height = height // pipeline.vae_spatial_compression_ratio
|
||||
latent_width = width // pipeline.vae_spatial_compression_ratio
|
||||
video_row_width = int(pipeline.vae_latent_channels * pipeline.patch_size[1] * pipeline.patch_size[2])
|
||||
|
||||
# The full Base schedule: ten steps at the checkpoint's sigma shifts, no distilled state
|
||||
# subsampling. The forward clock rides the Python-float timesteps while the update rides the
|
||||
# tensorized float32 sigma_t / ratio, mirroring the exact arithmetic chain of the reference
|
||||
# denoise loop bit for bit.
|
||||
video_sigmas = taomate_h3_select_time_shift_sigmas(shift_scale=TAOMATE_H3_VIDEO_SIGMA_SHIFT, num_steps=10)
|
||||
audio_sigmas = taomate_h3_select_time_shift_sigmas(shift_scale=TAOMATE_H3_AUDIO_SIGMA_SHIFT, num_steps=10)
|
||||
video_timesteps = [1.0 - sigma for sigma in video_sigmas[:-1]]
|
||||
audio_timesteps = [1.0 - sigma for sigma in audio_sigmas[:-1]]
|
||||
audio_sigmas_tensor = torch.tensor(audio_sigmas, dtype=torch.float32)
|
||||
audio_sigma_t = 1.0 - torch.tensor(audio_timesteps, dtype=torch.float32)
|
||||
audio_sigma_ratios = audio_sigmas_tensor[1:] / audio_sigmas_tensor[:-1]
|
||||
audio_one_minus_ratios = 1.0 - audio_sigma_ratios
|
||||
base_plan = taomate_h3_direct_5s_plan()
|
||||
|
||||
# The empty video stream: the audio-only path never executes the video projection or head.
|
||||
empty_video_rows = torch.zeros((0, video_row_width), dtype=torch.float32, device=device)
|
||||
|
||||
segments = []
|
||||
request_records = []
|
||||
prompt_cache = {}
|
||||
previous_clean = None
|
||||
previous_audio_latent_count = None
|
||||
for request_index in range(request_count):
|
||||
prompt_text = prompts[request_index]
|
||||
if prompt_text not in prompt_cache:
|
||||
# The transformer's 9 forwards keep it on the GPU under an offload mode; park it before
|
||||
# the conditioner comes in for its own pass (the teacher's explicit offload order).
|
||||
_park_on_cpu(pipeline.transformer)
|
||||
with torch.no_grad():
|
||||
prompt_cache[prompt_text] = pipeline.encode_prompt(
|
||||
prompt_text, device=device, dtype=pipeline.transformer.dtype
|
||||
)
|
||||
_park_on_cpu(pipeline.text_encoder)
|
||||
prompt_embeds, text_token_tags = prompt_cache[prompt_text]
|
||||
text_len = int(text_token_tags.shape[0])
|
||||
|
||||
active_plan = (
|
||||
base_plan
|
||||
if request_index == 0
|
||||
else taomate_h3_canonical_continuation_plan(base_plan, request_index=request_index)
|
||||
)
|
||||
active_audio_latents = active_plan.phases[-1].audio_latent_stop
|
||||
transport_prefix = TAOMATE_H3_REQUEST_AUDIO_LATENTS - active_audio_latents
|
||||
|
||||
official_audio = official_audio_noise(
|
||||
video_latent_t=TAOMATE_H3_REQUEST_VIDEO_LATENTS,
|
||||
video_latent_h=latent_height,
|
||||
video_latent_w=latent_width,
|
||||
audio_latent_t=TAOMATE_H3_REQUEST_AUDIO_LATENTS,
|
||||
seed=seed + request_index,
|
||||
)
|
||||
# A continuation slices its own fresh noise down to the steady geometry; the published
|
||||
# prefix of the request is the previous request's tail.
|
||||
target_noise = (
|
||||
official_audio.view(2, TAOMATE_H3_REQUEST_AUDIO_LATENTS, -1)[:, transport_prefix:]
|
||||
.contiguous()
|
||||
.view(-1, TAOMATE_H3_AUDIO_LATENT_CHANNELS)
|
||||
)
|
||||
reference_tail = (
|
||||
None
|
||||
if previous_clean is None
|
||||
else previous_clean.view(2, previous_audio_latent_count, -1)[
|
||||
:, -TAOMATE_H3_ROLLOVER_REFERENCE_LATENTS:
|
||||
]
|
||||
.contiguous()
|
||||
.view(2 * TAOMATE_H3_ROLLOVER_REFERENCE_LATENTS, TAOMATE_H3_AUDIO_LATENT_CHANNELS)
|
||||
)
|
||||
initial_audio = target_noise if reference_tail is None else torch.cat((reference_tail, target_noise), dim=0)
|
||||
ref_audio_t = 0 if reference_tail is None else TAOMATE_H3_ROLLOVER_REFERENCE_LATENTS
|
||||
ref_rows = ref_audio_t * 2
|
||||
|
||||
layout = audio_only_packed_layout(
|
||||
text_len,
|
||||
ref_audio_t,
|
||||
active_audio_latents,
|
||||
latent_height,
|
||||
latent_width,
|
||||
reference_time_start=text_len + previous_audio_latent_count - TAOMATE_H3_ROLLOVER_REFERENCE_LATENTS
|
||||
if reference_tail is not None
|
||||
else 0,
|
||||
target_time_start=text_len + (previous_audio_latent_count or 0),
|
||||
)
|
||||
position_ids = layout["position_ids"].to(device)
|
||||
token_tags = layout["token_tags"].to(device)
|
||||
text_indices = layout["text_indices"].to(device)
|
||||
audio_indices = layout["audio_indices"].to(device)
|
||||
|
||||
audio_rows = initial_audio.to(device=device, dtype=torch.float32)
|
||||
captured = {}
|
||||
|
||||
def run_forward(audio_rows, t_video, t_audio, has_reference):
|
||||
unique_timesteps, expand = audio_only_step_timesteps(t_video, t_audio, has_reference=has_reference)
|
||||
timestep_indices = expand(text_len, ref_rows, int(layout["sequence_length"])).to(device)
|
||||
_, audio_velocity = pipeline.transformer(
|
||||
hidden_states=empty_video_rows[None],
|
||||
audio_hidden_states=audio_rows[None],
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
timestep=unique_timesteps.to(device),
|
||||
timestep_indices=timestep_indices,
|
||||
token_tags=token_tags,
|
||||
position_ids=position_ids,
|
||||
video_indices=torch.empty(0, dtype=torch.long, device=device),
|
||||
audio_indices=audio_indices,
|
||||
text_indices=text_indices,
|
||||
return_dict=False,
|
||||
)
|
||||
return unique_timesteps, audio_velocity[0].float()
|
||||
|
||||
with torch.no_grad():
|
||||
for step in range(len(audio_timesteps)):
|
||||
_, audio_velocity = run_forward(
|
||||
audio_rows,
|
||||
video_timesteps[step],
|
||||
audio_timesteps[step],
|
||||
has_reference=ref_rows > 0,
|
||||
)
|
||||
# Euler over the target rows only; the reference rows stay clean.
|
||||
target = audio_rows[ref_rows:]
|
||||
sigma_t = float(audio_sigma_t[step])
|
||||
sigma_ratio = float(audio_sigma_ratios[step])
|
||||
one_minus_ratio = float(audio_one_minus_ratios[step])
|
||||
denoised = target + sigma_t * audio_velocity[ref_rows:]
|
||||
audio_rows = torch.cat(
|
||||
(
|
||||
audio_rows[:ref_rows],
|
||||
sigma_ratio * target + one_minus_ratio * denoised,
|
||||
),
|
||||
dim=0,
|
||||
)
|
||||
# The Base10 teacher contract: the clean audio rows after states 3, 6 and 9; state 9
|
||||
# is this request's final clean target.
|
||||
state_number = step + 1
|
||||
if state_number in TAOMATE_H3_TEACHER_STATE_NUMBERS:
|
||||
captured[state_number] = (
|
||||
audio_rows[ref_rows:].detach().to(device="cpu", dtype=torch.float32).contiguous()
|
||||
)
|
||||
|
||||
milestones = [captured[state_number] for state_number in TAOMATE_H3_TEACHER_STATE_NUMBERS]
|
||||
clean_target = milestones[-1]
|
||||
segments.append(clean_target)
|
||||
previous_clean = clean_target
|
||||
previous_audio_latent_count = active_audio_latents
|
||||
request_records.append(
|
||||
{
|
||||
"prompt": prompt_text,
|
||||
"audio_noise_seed": seed + request_index,
|
||||
"audio_latent_count": active_audio_latents,
|
||||
"transport_prefix": transport_prefix,
|
||||
"packed_text_rows": text_len,
|
||||
"packed_audio_rows": int(layout["audio_indices"].shape[0]),
|
||||
"reference_latents_per_channel": ref_audio_t,
|
||||
"milestones": milestones,
|
||||
}
|
||||
)
|
||||
print(
|
||||
f"[audio] request {request_index}: audio latents/channel={active_audio_latents}, "
|
||||
f"reference latents/channel={ref_audio_t}",
|
||||
flush=True,
|
||||
)
|
||||
|
||||
return torch.cat(segments, dim=0), request_records
|
||||
|
||||
|
||||
def write_teacher_artifact(output_dir, *, pipeline, request_records, request_count, seed, height, width):
|
||||
"""Write the offline Base10 teacher artifact the streaming runtime reads back.
|
||||
|
||||
The directory contract `TaomateH3TeacherArtifact.open` validates: `complete.json` plus one
|
||||
`request_XX.pt` per stream request, holding the request's `prompt` / `seed` /
|
||||
`audio_latent_count`, the contract keys (`teacher_state_numbers = (3, 6, 9)`,
|
||||
`stage3_target_state_indices = (16, 33, 49)`) and the three `(2 * audio_latent_count, 32)`
|
||||
float32 milestones captured in `generate_audio_track`.
|
||||
"""
|
||||
latent_height = height // pipeline.vae_spatial_compression_ratio
|
||||
latent_width = width // pipeline.vae_spatial_compression_ratio
|
||||
os.makedirs(output_dir, exist_ok=True)
|
||||
|
||||
for request_index, record in enumerate(request_records):
|
||||
torch.save(
|
||||
{
|
||||
"prompt": record["prompt"],
|
||||
"seed": seed,
|
||||
"audio_latent_count": record["audio_latent_count"],
|
||||
"teacher_state_numbers": TAOMATE_H3_TEACHER_STATE_NUMBERS,
|
||||
"stage3_target_state_indices": TAOMATE_H3_DISTILLED_STATE_INDICES[1:],
|
||||
"milestones": record["milestones"],
|
||||
},
|
||||
os.path.join(output_dir, f"request_{request_index:02d}.pt"),
|
||||
)
|
||||
|
||||
completion = {
|
||||
"mode": "base10_milestones",
|
||||
"strategy": "previous_clean_audio_tail_reference_then_new_noise",
|
||||
"partition": "fl2va",
|
||||
"base_precision": "bf16",
|
||||
"request_count": request_count,
|
||||
"request_seconds": 5,
|
||||
"request_seeds": [seed] * request_count,
|
||||
"audio_noise_seed_sequence": [record["audio_noise_seed"] for record in request_records],
|
||||
"producer_geometry": taomate_h3_teacher_geometry(
|
||||
width, height, video_latent_h=latent_height, video_latent_w=latent_width
|
||||
),
|
||||
"official_audio_latents_per_channel": TAOMATE_H3_REQUEST_AUDIO_LATENTS,
|
||||
"active_audio_latents_per_channel": [record["audio_latent_count"] for record in request_records],
|
||||
"request_receipts": [
|
||||
{
|
||||
"transport_prefix_audio_latents_per_channel": record["transport_prefix"],
|
||||
"packed_text_rows": record["packed_text_rows"],
|
||||
"packed_audio_rows": record["packed_audio_rows"],
|
||||
"reference_latents_per_channel": record["reference_latents_per_channel"],
|
||||
"reference_duration_seconds": 0.0 if record["reference_latents_per_channel"] == 0 else 1.0,
|
||||
"audio_noise_seed": record["audio_noise_seed"],
|
||||
"prefix_source_request": None if request_index == 0 else request_index - 1,
|
||||
}
|
||||
for request_index, record in enumerate(request_records)
|
||||
],
|
||||
"full_state_count": 10,
|
||||
"executed_forwards_per_request": 9,
|
||||
"teacher_state_numbers": list(TAOMATE_H3_TEACHER_STATE_NUMBERS),
|
||||
"stage3_target_state_indices": list(TAOMATE_H3_DISTILLED_STATE_INDICES[1:]),
|
||||
"artifact_storage_dtype": "float32",
|
||||
"video_rows": 0,
|
||||
"noise_order": "draw_and_discard_full_video_then_draw_audio",
|
||||
"reference_latents_per_channel": TAOMATE_H3_ROLLOVER_REFERENCE_LATENTS,
|
||||
"reference_duration_seconds": 1.0,
|
||||
"persistent_kv": False,
|
||||
"waveform_crossfade": False,
|
||||
"audio_vae_decode_count": 0,
|
||||
"adapter_loaded": False,
|
||||
}
|
||||
with open(os.path.join(output_dir, "complete.json"), "w", encoding="utf-8") as handle:
|
||||
json.dump(completion, handle, ensure_ascii=False, indent=2)
|
||||
handle.write("\n")
|
||||
|
||||
|
||||
# One continuous audio timeline 5 seconds at a time: every request after the first denoises the previous
|
||||
# request's clean tail as a frozen reference, and the captured 3/6/9 rows are the Base10 teacher artifact.
|
||||
audio_rows, request_records = generate_audio_track(
|
||||
pipeline,
|
||||
prompt=prompt,
|
||||
seed=seed,
|
||||
request_count=request_count,
|
||||
height=sample_size[0],
|
||||
width=sample_size[1],
|
||||
device=device,
|
||||
)
|
||||
|
||||
# Deliver the offline Base10 teacher artifact the streaming runtime consumes: these are exactly the
|
||||
# rows `TaomateH3TeacherArtifact.open` reads back, so `predict_t2av_streaming.py` can point its
|
||||
# `audio_teacher_dir` straight at this directory.
|
||||
if audio_teacher_dir is not None:
|
||||
write_teacher_artifact(
|
||||
audio_teacher_dir,
|
||||
pipeline=pipeline,
|
||||
request_records=request_records,
|
||||
request_count=request_count,
|
||||
seed=seed,
|
||||
height=sample_size[0],
|
||||
width=sample_size[1],
|
||||
)
|
||||
print(
|
||||
f"saved Base10 teacher artifact: {audio_teacher_dir} "
|
||||
f"({request_count} request(s), base_precision=bf16)",
|
||||
flush=True,
|
||||
)
|
||||
|
||||
# One-shot publication, exactly like the streaming pipeline's own ending: splice the requests
|
||||
# (already prefix-free) and decode the full timeline once.
|
||||
total_audio_latents = int(audio_rows.shape[0]) // 2
|
||||
_park_on_cpu(pipeline.transformer)
|
||||
with torch.no_grad():
|
||||
audio = pipeline.decode_audio_latents(audio_rows.to(device), 0, total_audio_latents)
|
||||
|
||||
waveform = audio[0].float().cpu()
|
||||
sample_rate = pipeline.audio_sampling_rate
|
||||
duration = waveform.shape[-1] / sample_rate
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
audio_path = os.path.join(save_path, prefix + ".wav")
|
||||
torchaudio.save(audio_path, waveform, sample_rate)
|
||||
print(
|
||||
f"saved {audio_path}: {total_audio_latents} latents/channel, {duration:.3f}s @ {sample_rate} Hz, "
|
||||
f"{waveform.shape[0]} channels",
|
||||
flush=True,
|
||||
)
|
||||
|
||||
save_results()
|
||||
@@ -0,0 +1,299 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import torch
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices
|
||||
from videox_fun.models import (AutoencoderKLMiniMaxH3,
|
||||
AutoencoderKLMiniMaxH3Audio,
|
||||
MiniMaxH3Transformer3DModel, Qwen2TokenizerFast,
|
||||
Qwen3VLForConditionalGeneration,
|
||||
Qwen3VLProcessor)
|
||||
from videox_fun.pipeline import MiniMaxH3StreamingPipeline
|
||||
from videox_fun.utils import (MiniMaxH3Scheduler, register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import save_videos_with_audio_grid
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
# The transformer alone is 61.7 GB in bfloat16 and the Qwen3-VL conditioner another 62.1 GB; with the persistent
|
||||
# streaming K/V cache on top, both model_cpu_offload and model_cpu_offload_and_qfloat8 exceed a single 80 GB card
|
||||
# (measured OOM), so model_group_offload is the verified default for one-card streaming.
|
||||
GPU_memory_mode = "model_group_offload"
|
||||
# Multi GPUs config. Streaming inference runs the whole attention sequence on one GPU (the persistent
|
||||
# K/V cache must stay whole-sequence on one device), so keep ulysses_degree = ring_degree = 1 and the
|
||||
# FSDP switches off. To generate many prompts with one prompt per GPU, use
|
||||
# `examples/taomate_h3/_predict_t2av_streaming_list.py` instead.
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = False
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/MiniMax-H3"
|
||||
|
||||
# Load pretrained model if need
|
||||
# A full finetune goes in `transformer_path` (a training checkpoint's `transformer` folder or a single
|
||||
# safetensors file). A LoRA goes in `lora_path`, which accepts either a kohya safetensors checkpoint (e.g. the
|
||||
# output of `scripts/taomate_h3/train_distill_lora.py`) or the *official* TaoMate-H3 adapter directory:
|
||||
# `merge_lora` tells the two apart (a directory vs a file) and converts the official adapter to the kohya
|
||||
# layout on the fly.
|
||||
transformer_path = None
|
||||
vae_path = None
|
||||
# The official TaoMate-H3 adapter (rank 128 / alpha 128, the step-3000 generator EMA) from
|
||||
# `TaoLiveAIGC/TaoMate-H3`. The distilled 3-step schedule is this adapter's own behaviour, so it is on by
|
||||
# default — the bare base weights do not reproduce the official runtime. Download it first with:
|
||||
# hf download TaoLiveAIGC/TaoMate-H3 --include "config.json" "adapter_config.json" "adapter_model.safetensors" \
|
||||
# --local-dir models/Diffusion_Transformer/TaoMate-H3-adapter
|
||||
lora_path = "models/Diffusion_Transformer/TaoMate-H3-adapter"
|
||||
|
||||
# Other params
|
||||
# The canvas: the short edge must be 480, 768 or 1088 and both edges 32-aligned (480x864 is the
|
||||
# resolution the official TaoMate-H3 demo ships). The teacher artifact is bound to this geometry.
|
||||
sample_size = [864, 480]
|
||||
# How many 5-second stream requests to generate: the first one runs the direct 124-frame plan, every
|
||||
# following one the canonical 119-frame continuation spliced behind its predecessor. One prompt covers
|
||||
# the whole timeline.
|
||||
request_count = 2
|
||||
fps = 24
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# The prompt the default Base10 teacher artifact (`samples/taomate_h3_teacher/00000000`) was generated for —
|
||||
# `Self-Forcing/prompts/self_forcing_all_prompts.json` entry 0. A list gives one prompt per stream request
|
||||
# (the official `--prompt-json` shape); the artifact must then carry exactly those prompts.
|
||||
prompt = (
|
||||
"A stylish woman strolls down a bustling Tokyo street, the warm glow of neon lights and animated city "
|
||||
"signs casting vibrant reflections. She wears a sleek black leather jacket paired with a flowing red "
|
||||
"dress and black boots, her black purse slung over her shoulder. Sunglasses perched on her nose and a "
|
||||
"bold red lipstick add to her confident, casual demeanor. The street is damp and reflective, creating a "
|
||||
"mirror-like effect that enhances the colorful lights and shadows. Pedestrians move about, adding to the "
|
||||
"lively atmosphere. The scene is captured in a dynamic medium shot with the woman walking slightly to "
|
||||
"one side, highlighting her graceful strides."
|
||||
)
|
||||
# The authored seed. Request i draws its video noise from seed + i * 1000003; the audio noise seeds come
|
||||
# from the teacher artifact, so the artifact must have been generated for this very seed.
|
||||
seed = 43
|
||||
# The offline Base10 audio-teacher artifact directory produced by `examples/taomate_h3/predict_audio.py`
|
||||
# for exactly this prompt, seed and resolution (set the same value in its `audio_teacher_dir` knob; the
|
||||
# producer runs audio-only base-weight forwards, no video decode). Generate it before the first run.
|
||||
audio_teacher_dir = "samples/taomate_h3_teacher/00000000"
|
||||
# Merge weight of `lora_path`. The official TaoMate-H3 adapter ships alpha == rank, so 1.0 reproduces the
|
||||
# official runtime; lower it (e.g. 0.55) when blending a kohya finetune checkpoint instead.
|
||||
lora_weight = 0.55
|
||||
save_path = "samples/taomate-h3-videos-t2av-streaming"
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
|
||||
# `model_name` may point either at a converted diffusers layout or at an *original* MiniMax-H3 partition (e.g.
|
||||
# `MiniMax-H3/FL2VA`); the original shards are converted on the fly while loading, no intermediate copy on disk.
|
||||
# Transformer
|
||||
transformer = MiniMaxH3Transformer3DModel.from_pretrained(
|
||||
model_name,
|
||||
subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if os.path.isdir(transformer_path):
|
||||
# A training checkpoint's `transformer` folder carries its own config.json, so the loader restores the
|
||||
# mixed-precision contract of the checkpoint (`_keep_in_fp32_modules`) by itself.
|
||||
transformer = MiniMaxH3Transformer3DModel.from_pretrained(
|
||||
transformer_path,
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
else:
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
# `strict=False` accepts a file whose keys belong to another model — a LoRA checkpoint, say — by loading
|
||||
# nothing at all and silently generating with the base weights, so an unexpected key is a hard error.
|
||||
assert len(u) == 0, (
|
||||
f"{transformer_path} holds {len(u)} key(s) the transformer does not have, e.g. {u[:3]}. A LoRA "
|
||||
"checkpoint belongs in `lora_path`, not `transformer_path`."
|
||||
)
|
||||
|
||||
# Video VAE. The released weights are float32 and the decode runs under float16 autocast, so the VAE is not
|
||||
# downcast even when the rest of the pipeline is bfloat16 (this is also how the training scripts load it).
|
||||
vae = AutoencoderKLMiniMaxH3.from_pretrained(
|
||||
model_name,
|
||||
subfolder="vae",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Audio VAE, waveform in / waveform out: MiniMax-H3 has no separate vocoder. Float32 as released, like the video VAE.
|
||||
audio_vae = AutoencoderKLMiniMaxH3Audio.from_pretrained(
|
||||
model_name,
|
||||
subfolder="audio_vae",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
|
||||
# Get Tokenizer and Processor
|
||||
tokenizer = Qwen2TokenizerFast.from_pretrained(os.path.join(model_name, "tokenizer"))
|
||||
processor = Qwen3VLProcessor.from_pretrained(os.path.join(model_name, "processor"))
|
||||
|
||||
# Get Text encoder. MiniMax-H3 reads the unnormalized hidden state after the 50th decoder layer of Qwen3-VL.
|
||||
text_encoder = Qwen3VLForConditionalGeneration.from_pretrained(
|
||||
os.path.join(model_name, "text_encoder"),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Schedulers. The streaming pipeline overrides the step counts internally (the distilled 3-step video
|
||||
# schedule and the teacher-anchored audio schedule), so the checkpoint schedules only seed the class.
|
||||
scheduler = MiniMaxH3Scheduler.from_pretrained(model_name, subfolder="scheduler")
|
||||
audio_scheduler = MiniMaxH3Scheduler.from_pretrained(model_name, subfolder="audio_scheduler")
|
||||
|
||||
pipeline = MiniMaxH3StreamingPipeline(
|
||||
vae=vae,
|
||||
audio_vae=audio_vae,
|
||||
text_encoder=text_encoder,
|
||||
tokenizer=tokenizer,
|
||||
processor=processor,
|
||||
transformer=transformer,
|
||||
scheduler=scheduler,
|
||||
audio_scheduler=audio_scheduler,
|
||||
)
|
||||
|
||||
# The float32 modules of the mixed-precision checkpoint stay untouched by the float8 quantization.
|
||||
fp8_exclude_module_name = [
|
||||
"proj_in", "audio_proj_in", "context_embedder", "time_embedder", "time_proj",
|
||||
"token_refiner", "norm_out", "proj_out", "audio_proj_out",
|
||||
]
|
||||
use_qfloat8 = "qfloat8" in GPU_memory_mode
|
||||
if use_qfloat8:
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=fp8_exclude_module_name, device=device)
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.transformer_blocks)):
|
||||
pipeline.transformer.transformer_blocks[i] = torch.compile(pipeline.transformer.transformer_blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_weight_dtype_wrapper(pipeline.transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
# Merge LoRA through the standard entry point: `merge_lora` detects an official TaoMate-H3 adapter
|
||||
# directory and converts it to the kohya layout on the fly, and takes a kohya safetensors checkpoint
|
||||
# as before; no CFG pass is run either way.
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
else:
|
||||
print(
|
||||
"WARNING: no LoRA is loaded. The 3-step distilled schedule expects the official TaoMate-H3 adapter "
|
||||
"(`lora_path`, e.g. models/Diffusion_Transformer/TaoMate-H3-adapter); the bare base weights do not reproduce the "
|
||||
"official runtime and the result will be visibly off.",
|
||||
flush=True,
|
||||
)
|
||||
|
||||
# One continuous video + soundtrack 5 seconds at a time: each request reuses the cleaned audio/video K/V
|
||||
# of everything before it (full-sequence attention, no re-encoding), the video denoises in the distilled
|
||||
# 3-step schedule, and the audio is anchored by the *offline* Base10 teacher artifact.
|
||||
with torch.no_grad():
|
||||
output = pipeline(
|
||||
prompt=prompt,
|
||||
audio_teacher_dir=audio_teacher_dir,
|
||||
height=None if sample_size is None else sample_size[0],
|
||||
width=None if sample_size is None else sample_size[1],
|
||||
request_count=request_count,
|
||||
seed=seed,
|
||||
output_type="pt",
|
||||
)
|
||||
print(f"[{os.environ.get('RANK', '0')}] generation done, decoding", flush=True)
|
||||
|
||||
# Restore the merged weights after generation: both the official adapter directory and the kohya
|
||||
# checkpoint go through the same `unmerge_lora` path.
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
for receipt in output.request_receipts:
|
||||
plan = receipt["plan"]
|
||||
print(
|
||||
f"request {receipt['request_index']}: continuation={receipt['canonical_continuation']}, "
|
||||
f"phases={len(plan['phases'])}, published video latents={receipt['published_video_latents']}, "
|
||||
f"audio latents/channel={receipt['published_audio_latents_per_channel']}, "
|
||||
f"retained history={receipt['retained_history_tokens']} tokens"
|
||||
)
|
||||
|
||||
sample = output.videos
|
||||
audio = output.audio
|
||||
audio_sample_rate = output.sampling_rate
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_with_audio_grid(sample, audio, video_path, fps=fps, audio_sample_rate=audio_sample_rate)
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
# Keep every rank alive until the saving rank finishes; an early exit of one rank makes the elastic launcher
|
||||
# terminate the others.
|
||||
dist.barrier()
|
||||
else:
|
||||
save_results()
|
||||
@@ -0,0 +1,335 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
from transformers import AutoTokenizer
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderTinyWan,
|
||||
AutoTokenizer, CLIPModel,
|
||||
WanT5EncoderModel, WanTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanI2VPipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "sequential_cpu_offload"
|
||||
# Multi GPUs config
|
||||
# Please ensure that the product of ulysses_degree and ring_degree equals the number of GPUs used.
|
||||
# For example, if you are using 8 GPUs, you can set ulysses_degree = 2 and ring_degree = 4.
|
||||
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = True
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with the fsdp_dit and sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# Support TeaCache.
|
||||
enable_teacache = True
|
||||
# Recommended to be set between 0.05 and 0.30. A larger threshold can cache more steps, speeding up the inference process,
|
||||
# but it may cause slight differences between the generated content and the original content.
|
||||
# # --------------------------------------------------------------------------------------------------- #
|
||||
# | Model Name | threshold | Model Name | threshold | Model Name | threshold |
|
||||
# | Wan2.1-T2V-1.3B | 0.05~0.10 | Wan2.1-T2V-14B | 0.10~0.15 | Wan2.1-I2V-14B-720P | 0.20~0.30 |
|
||||
# | Wan2.1-I2V-14B-480P | 0.20~0.25 | Wan2.1-Fun-*-1.3B-* | 0.05~0.10 | Wan2.1-Fun-*-14B-* | 0.20~0.30 |
|
||||
# # --------------------------------------------------------------------------------------------------- #
|
||||
teacache_threshold = 0.10
|
||||
# The number of steps to skip TeaCache at the beginning of the inference process, which can
|
||||
# reduce the impact of TeaCache on generated video quality.
|
||||
num_skip_start_steps = 5
|
||||
# Whether to offload TeaCache tensors to cpu to save a little bit of GPU memory.
|
||||
teacache_offload = False
|
||||
|
||||
# Skip some cfg steps in inference
|
||||
# Recommended to be set between 0.00 and 0.25
|
||||
cfg_skip_ratio = 0
|
||||
|
||||
# Riflex config
|
||||
enable_riflex = False
|
||||
# Index of intrinsic frequency
|
||||
riflex_k = 6
|
||||
|
||||
# Config and model path
|
||||
config_path = "config/wan2.1/wan_civitai.yaml"
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/Wan2.1-I2V-14B-480P"
|
||||
|
||||
# TAE (Tiny AutoEncoder) config.
|
||||
# TAE shares the exact latent space of the full Wan2.1 VAE but encodes / decodes
|
||||
# much faster and cheaper (<0.5GB vs ~6-9GB peak memory), at the cost of some
|
||||
# fine detail. It is suited for live previewing or low-memory decoding.
|
||||
# Weights come from https://github.com/madebyollin/taehv (taew2_1.safetensors for the
|
||||
# Wan2.1 / Wan2.2 14B 16ch latent).
|
||||
# The tae_path can be a path relative to model_name or an absolute path;
|
||||
# latent channels / patch size / compression ratios are inferred from it.
|
||||
tae_path = "taew2_1.safetensors"
|
||||
|
||||
# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
|
||||
sampler_name = "Flow_Unipc"
|
||||
# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
|
||||
# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
|
||||
# If you want to generate a 480p video, it is recommended to set the shift value to 3.0.
|
||||
# If you want to generate a 720p video, it is recommended to set the shift value to 5.0.
|
||||
shift = 3
|
||||
|
||||
# Load pretrained model if need
|
||||
transformer_path = None
|
||||
vae_path = None
|
||||
lora_path = None
|
||||
|
||||
# Other params
|
||||
sample_size = [480, 832]
|
||||
video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
|
||||
# prompts
|
||||
prompt = "一只棕色的狗摇着头,坐在舒适房间里的浅色沙发上。在狗的后面,架子上有一幅镶框的画,周围是粉红色的花朵。房间里柔和温暖的灯光营造出舒适的氛围。"
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
guidance_scale = 6.0
|
||||
seed = 43
|
||||
num_inference_steps = 50
|
||||
lora_weight = 0.55
|
||||
save_path = "samples/wan-videos-i2v-tae"
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
config = OmegaConf.load(config_path)
|
||||
# Override the VAE with AutoencoderTinyWan (TAE); everything else (latent
|
||||
# channels, patch size, compression ratios) is inferred from the weight file.
|
||||
config['vae_kwargs'] = OmegaConf.create({
|
||||
'vae_type': 'AutoencoderTinyWan',
|
||||
'vae_subpath': tae_path,
|
||||
})
|
||||
|
||||
transformer = WanTransformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Vae
|
||||
Chosen_AutoencoderKL = {
|
||||
"AutoencoderKLWan": AutoencoderKLWan,
|
||||
"AutoencoderTinyWan": AutoencoderTinyWan
|
||||
}[config['vae_kwargs'].get('vae_type', 'AutoencoderKLWan')]
|
||||
vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
|
||||
additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
if isinstance(vae, AutoencoderTinyWan):
|
||||
state_dict = vae.model.patch_tgrow_layers(state_dict)
|
||||
m, u = vae.model.load_state_dict(state_dict, strict=False)
|
||||
else:
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Tokenizer
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
|
||||
)
|
||||
|
||||
# Get Text encoder
|
||||
text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
|
||||
additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Clip Image Encoder
|
||||
clip_image_encoder = CLIPModel.from_pretrained(
|
||||
os.path.join(model_name, config['image_encoder_kwargs'].get('image_encoder_subpath', 'image_encoder')),
|
||||
).to(weight_dtype)
|
||||
clip_image_encoder = clip_image_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
}[sampler_name]
|
||||
if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
|
||||
config['scheduler_kwargs']['shift'] = 1
|
||||
scheduler = Chosen_Scheduler(
|
||||
**filter_kwargs(Chosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
|
||||
)
|
||||
|
||||
# Get Pipeline
|
||||
pipeline = WanI2VPipeline(
|
||||
transformer=transformer,
|
||||
vae=vae,
|
||||
tokenizer=tokenizer,
|
||||
text_encoder=text_encoder,
|
||||
scheduler=scheduler,
|
||||
clip_image_encoder=clip_image_encoder
|
||||
)
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.blocks)):
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
|
||||
pipeline.transformer.enable_teacache(
|
||||
coefficients, num_inference_steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
|
||||
)
|
||||
|
||||
if cfg_skip_ratio is not None:
|
||||
print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
|
||||
pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, num_inference_steps)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
with torch.no_grad():
|
||||
video_length = int((video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
|
||||
latent_frames = (video_length - 1) // vae.config.temporal_compression_ratio + 1
|
||||
|
||||
if enable_riflex:
|
||||
pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
|
||||
|
||||
input_video, input_video_mask, clip_image = get_image_to_video_latent(validation_image_start, None, video_length=video_length, sample_size=sample_size)
|
||||
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
num_frames = video_length,
|
||||
negative_prompt = negative_prompt,
|
||||
height = sample_size[0],
|
||||
width = sample_size[1],
|
||||
generator = generator,
|
||||
guidance_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
|
||||
video = input_video,
|
||||
mask_video = input_video_mask,
|
||||
clip_image = clip_image,
|
||||
shift = shift,
|
||||
).videos
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
if video_length == 1:
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
|
||||
image = sample[0, :, 0]
|
||||
image = image.transpose(0, 1).transpose(1, 2)
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
else:
|
||||
save_results()
|
||||
@@ -0,0 +1,316 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderTinyWan,
|
||||
AutoTokenizer, WanT5EncoderModel,
|
||||
WanTransformer3DModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import WanPipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "sequential_cpu_offload"
|
||||
# Multi GPUs config
|
||||
# Please ensure that the product of ulysses_degree and ring_degree equals the number of GPUs used.
|
||||
# For example, if you are using 8 GPUs, you can set ulysses_degree = 2 and ring_degree = 4.
|
||||
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = True
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with the fsdp_dit and sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# TeaCache config
|
||||
enable_teacache = True
|
||||
# Recommended to be set between 0.05 and 0.30. A larger threshold can cache more steps, speeding up the inference process,
|
||||
# but it may cause slight differences between the generated content and the original content.
|
||||
# # --------------------------------------------------------------------------------------------------- #
|
||||
# | Model Name | threshold | Model Name | threshold | Model Name | threshold |
|
||||
# | Wan2.1-T2V-1.3B | 0.05~0.10 | Wan2.1-T2V-14B | 0.10~0.15 | Wan2.1-I2V-14B-720P | 0.20~0.30 |
|
||||
# | Wan2.1-I2V-14B-480P | 0.20~0.25 | Wan2.1-Fun-*-1.3B-* | 0.05~0.10 | Wan2.1-Fun-*-14B-* | 0.20~0.30 |
|
||||
# # --------------------------------------------------------------------------------------------------- #
|
||||
teacache_threshold = 0.10
|
||||
# The number of steps to skip TeaCache at the beginning of the inference process, which can
|
||||
# reduce the impact of TeaCache on generated video quality.
|
||||
num_skip_start_steps = 5
|
||||
# Whether to offload TeaCache tensors to cpu to save a little bit of GPU memory.
|
||||
teacache_offload = False
|
||||
|
||||
# Skip some cfg steps in inference
|
||||
# Recommended to be set between 0.00 and 0.25
|
||||
cfg_skip_ratio = 0
|
||||
|
||||
# Riflex config
|
||||
enable_riflex = False
|
||||
# Index of intrinsic frequency
|
||||
riflex_k = 6
|
||||
|
||||
# Config and model path
|
||||
config_path = "config/wan2.1/wan_civitai.yaml"
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/Wan2.1-T2V-1.3B"
|
||||
|
||||
# TAE (Tiny AutoEncoder) config.
|
||||
# TAE shares the exact latent space of the full Wan2.1 VAE but encodes / decodes
|
||||
# much faster and cheaper (<0.5GB vs ~6-9GB peak memory), at the cost of some
|
||||
# fine detail. It is suited for live previewing or low-memory decoding.
|
||||
# Weights come from https://github.com/madebyollin/taehv (taew2_1.safetensors for the
|
||||
# Wan2.1 / Wan2.2 14B 16ch latent).
|
||||
# The tae_path can be a path relative to model_name or an absolute path;
|
||||
# latent channels / patch size / compression ratios are inferred from it.
|
||||
tae_path = "taew2_1.safetensors"
|
||||
|
||||
# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
|
||||
sampler_name = "Flow_Unipc"
|
||||
# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
|
||||
# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
|
||||
# If you want to generate a 480p video, it is recommended to set the shift value to 3.0.
|
||||
# If you want to generate a 720p video, it is recommended to set the shift value to 5.0.
|
||||
shift = 3
|
||||
|
||||
# Load pretrained model if need
|
||||
transformer_path = None
|
||||
vae_path = None
|
||||
lora_path = None
|
||||
|
||||
# Other params
|
||||
sample_size = [480, 832]
|
||||
video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "一只棕色的狗摇着头,坐在舒适房间里的浅色沙发上。在狗的后面,架子上有一幅镶框的画,周围是粉红色的花朵。房间里柔和温暖的灯光营造出舒适的氛围。"
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
guidance_scale = 6.0
|
||||
seed = 43
|
||||
num_inference_steps = 50
|
||||
lora_weight = 0.55
|
||||
save_path = "samples/wan-videos-t2v-tae"
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
config = OmegaConf.load(config_path)
|
||||
# Override the VAE with AutoencoderTinyWan (TAE); everything else (latent
|
||||
# channels, patch size, compression ratios) is inferred from the weight file.
|
||||
config['vae_kwargs'] = OmegaConf.create({
|
||||
'vae_type': 'AutoencoderTinyWan',
|
||||
'vae_subpath': tae_path,
|
||||
})
|
||||
|
||||
transformer = WanTransformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Vae
|
||||
Chosen_AutoencoderKL = {
|
||||
"AutoencoderKLWan": AutoencoderKLWan,
|
||||
"AutoencoderTinyWan": AutoencoderTinyWan
|
||||
}[config['vae_kwargs'].get('vae_type', 'AutoencoderKLWan')]
|
||||
vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
|
||||
additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
if isinstance(vae, AutoencoderTinyWan):
|
||||
state_dict = vae.model.patch_tgrow_layers(state_dict)
|
||||
m, u = vae.model.load_state_dict(state_dict, strict=False)
|
||||
else:
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Tokenizer
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
|
||||
)
|
||||
|
||||
# Get Text encoder
|
||||
text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
|
||||
additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
}[sampler_name]
|
||||
if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
|
||||
config['scheduler_kwargs']['shift'] = 1
|
||||
scheduler = Chosen_Scheduler(
|
||||
**filter_kwargs(Chosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
|
||||
)
|
||||
|
||||
# Get Pipeline
|
||||
pipeline = WanPipeline(
|
||||
transformer=transformer,
|
||||
vae=vae,
|
||||
tokenizer=tokenizer,
|
||||
text_encoder=text_encoder,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.blocks)):
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
|
||||
pipeline.transformer.enable_teacache(
|
||||
coefficients, num_inference_steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
|
||||
)
|
||||
|
||||
if cfg_skip_ratio is not None:
|
||||
print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
|
||||
pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, num_inference_steps)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
with torch.no_grad():
|
||||
video_length = int((video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
|
||||
latent_frames = (video_length - 1) // vae.config.temporal_compression_ratio + 1
|
||||
|
||||
if enable_riflex:
|
||||
pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
|
||||
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
num_frames = video_length,
|
||||
negative_prompt = negative_prompt,
|
||||
height = sample_size[0],
|
||||
width = sample_size[1],
|
||||
generator = generator,
|
||||
guidance_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
shift = shift,
|
||||
).videos
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
if video_length == 1:
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
|
||||
image = sample[0, :, 0]
|
||||
image = image.transpose(0, 1).transpose(1, 2)
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
else:
|
||||
save_results()
|
||||
@@ -0,0 +1,343 @@
|
||||
import os
|
||||
import sys
|
||||
import time
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
WanT5EncoderModel,
|
||||
WanTransformer3DModel_FlexForcing)
|
||||
from videox_fun.pipeline import WanFlexForcingPipeline
|
||||
from videox_fun.pipeline.pipeline_wan_flex_forcing import \
|
||||
PAPER_CHUNK_CONFIGS
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import filter_kwargs, save_videos_grid
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "model_full_load"
|
||||
# Multi GPUs config
|
||||
# Please ensure that the product of ulysses_degree and ring_degree equals the number of GPUs used.
|
||||
# For example, if you are using 8 GPUs, you can set ulysses_degree = 2 and ring_degree = 4.
|
||||
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = True
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with the fsdp_dit and sequential_cpu_offload.
|
||||
# [NOTE]: flex_attention block masks are rebuilt per partition, so compiling the
|
||||
# blocks only pays off when the ladder (`denoise_mode`, `num_inference_steps`)
|
||||
# is fixed.
|
||||
compile_dit = False
|
||||
|
||||
# Config and model path
|
||||
config_path = "config/wan2.1/wan_civitai.yaml"
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/Wan2.1-T2V-1.3B"
|
||||
|
||||
# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
|
||||
sampler_name = "Flow"
|
||||
# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
|
||||
# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
|
||||
shift = 5
|
||||
|
||||
# Load pretrained model if need
|
||||
# Any Wan2.1 / CausVid / Self-Forcing checkpoint loads as-is: the Flex-Forcing
|
||||
# backbone inherits every parameter name and only the new `flex_kproj.*` tensors
|
||||
# are reported missing (they are identity-initialised, so step 0 is unchanged).
|
||||
transformer_path = "output_dir_wan2.1_flex_forcing_distill/checkpoint-1000/diffusion_pytorch_model.safetensors"
|
||||
vae_path = None
|
||||
lora_path = None
|
||||
|
||||
# Other params
|
||||
# The paper evaluates 5 s clips: 81 pixel frames = 21 latent frames at 832x432.
|
||||
sample_size = [432, 832]
|
||||
video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Flex-Forcing (arXiv 2607.03509) inference config
|
||||
# --- Does the frame partition change with the noise level? -----------------
|
||||
# "fixed" -> one partition held for every denoising step, i.e. the
|
||||
# block-major Self-Forcing schedule (use `num_frame_per_block`).
|
||||
# "pyramid" -> Flex-Forcing 3.2: level 0 plans the whole clip in one
|
||||
# bidirectional chunk, each further denoising step binary-splits
|
||||
# every chunk - coarse (planning) -> fine (refinement), one level
|
||||
# per step. The depth follows `num_inference_steps` automatically,
|
||||
# so there is no second number to keep in sync. Levels only ever
|
||||
# *add* boundaries, so a KV cache written at a coarse level stays
|
||||
# valid at a finer one.
|
||||
# An int instead pins a truncated pyramid of exactly that many levels; for 21
|
||||
# latent frames (= 81 pixel frames) that ladder is
|
||||
# 2 -> [[21], [11, 10]] 3 -> [[21], [11, 10], [6, 5, 5, 5]]
|
||||
denoise_mode = "pyramid"
|
||||
# How far the splitting above goes: every chunk is binary-split until it is at
|
||||
# or below this block size, so it decides how causal the finest level is.
|
||||
# 1 -> leaves are single frames, fully causal
|
||||
# 3 -> leaves stay 3-frame blocks (classic Self-Forcing granularity); the
|
||||
# ladder then converges early and later steps reuse its finest level.
|
||||
min_num_frame_per_block = 1
|
||||
# Advanced: the 3.1 partition itself can also be pinned on the pipeline call
|
||||
# (`chunk_spec = "18-3" / "ar" / "uniform:3"`); the pyramid above does not need
|
||||
# it, since it derives every level from the whole-clip level 0.
|
||||
# 3.3's K-Projection (the noise-level aligned Pi_{t<-0} of the cached clean keys)
|
||||
# is deliberately not configurable here: the model builds `diag_rank1` and applies
|
||||
# it on every call, so there is nothing left to set.
|
||||
# --- Causal backbone (inherited from Self-Forcing) -------------------------
|
||||
# `num_frame_per_block` only takes effect once the pyramid is off; the rollout
|
||||
# derives the block size from the partition itself otherwise. `context_noise`
|
||||
# is the noise level the clean context is committed at.
|
||||
num_frame_per_block = 3
|
||||
independent_first_frame = False
|
||||
context_noise = 0.0
|
||||
# Local attention window size (-1 for global attention). Must stay -1 whenever
|
||||
# the pyramid is used, because a rolling window evicts by `current_start` deltas
|
||||
# that a splitting chunk moves backwards. For long videos the paper uses a
|
||||
# 21-latent-frame window with a 3-frame sink: local_attn_size = 21, sink_size = 3.
|
||||
local_attn_size = -1
|
||||
sink_size = 0
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "A stylish woman walks down a Tokyo street filled with warm glowing neon and animated city signage. She wears a black leather jacket, a long red dress, and black boots, and carries a black purse. She wears sunglasses and red lipstick. She walks confidently and casually. The street is damp and reflective, creating a mirror effect of the colorful lights. Many pedestrians walk about."
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
guidance_scale = 1.0
|
||||
seed = 43
|
||||
# The paper's 2-step DMD model denoises at [1000, 500]; 4 steps ([1000, 750,
|
||||
# 500, 250]) suit the CCD checkpoint. `denoise_mode = "pyramid"` uses one ladder
|
||||
# level per step here, so a deeper pyramid just wants more steps.
|
||||
num_inference_steps = 4
|
||||
lora_weight = 0.55
|
||||
save_path = "samples/wan-videos-flex-forcing-t2v"
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
config = OmegaConf.load(config_path)
|
||||
|
||||
# Load transformer with the Flex-Forcing backbone
|
||||
transformer_additional_kwargs = OmegaConf.to_container(config['transformer_additional_kwargs'])
|
||||
transformer_additional_kwargs['local_attn_size'] = local_attn_size
|
||||
transformer_additional_kwargs['sink_size'] = sink_size
|
||||
|
||||
transformer = WanTransformer3DModel_FlexForcing.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=transformer_additional_kwargs,
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
state_dict = state_dict["generator_ema"] if "generator_ema" in state_dict else state_dict
|
||||
state_dict = state_dict["generator"] if "generator" in state_dict else state_dict
|
||||
if any("._fsdp_wrapped_module." in k for k in state_dict.keys()):
|
||||
state_dict = {k.replace("model._fsdp_wrapped_module.", "model.", 1) if k.startswith("model._fsdp_wrapped_module.") else k: v for k, v in state_dict.items()}
|
||||
if any(k.startswith("model.") for k in state_dict.keys()):
|
||||
state_dict = {k.replace("model.", "", 1) if k.startswith("model.") else k: v for k, v in state_dict.items()}
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
# `flex_kproj.*` is expected to be missing when loading a Self-Forcing /
|
||||
# CausVid checkpoint that predates Flex-Forcing.
|
||||
other_missing = [k for k in m if "flex_kproj" not in k]
|
||||
print(f"missing keys: {len(m)} ({len(m) - len(other_missing)} of them flex_kproj), "
|
||||
f"unexpected keys: {len(u)}")
|
||||
|
||||
# Get Vae
|
||||
vae = AutoencoderKLWan.from_pretrained(
|
||||
os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
|
||||
additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Tokenizer
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
|
||||
)
|
||||
|
||||
# Get Text encoder
|
||||
text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
|
||||
additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
}[sampler_name]
|
||||
if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
|
||||
config['scheduler_kwargs']['shift'] = 1
|
||||
scheduler = Chosen_Scheduler(
|
||||
**filter_kwargs(Chosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
|
||||
)
|
||||
|
||||
# Get Pipeline
|
||||
pipeline = WanFlexForcingPipeline(
|
||||
transformer=transformer,
|
||||
vae=vae,
|
||||
tokenizer=tokenizer,
|
||||
text_encoder=text_encoder,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.blocks)):
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
print(f"[Flex-Forcing] denoise_mode={denoise_mode}, "
|
||||
f"min_num_frame_per_block={min_num_frame_per_block}, "
|
||||
f"local_attn_size={local_attn_size}, sink_size={sink_size}")
|
||||
print(f"[Flex-Forcing] partitions measured in the paper: "
|
||||
f"{[list(c) for c in PAPER_CHUNK_CONFIGS]}")
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
with torch.no_grad():
|
||||
video_length = int((video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
|
||||
latent_frames = (video_length - 1) // vae.config.temporal_compression_ratio + 1
|
||||
|
||||
torch.cuda.synchronize()
|
||||
start_time = time.time()
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
num_frames = video_length,
|
||||
negative_prompt = negative_prompt,
|
||||
height = sample_size[0],
|
||||
width = sample_size[1],
|
||||
generator = generator,
|
||||
guidance_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
shift = shift,
|
||||
num_frame_per_block = num_frame_per_block,
|
||||
independent_first_frame = independent_first_frame,
|
||||
context_noise = context_noise,
|
||||
denoise_mode = denoise_mode,
|
||||
min_num_frame_per_block = min_num_frame_per_block,
|
||||
).videos
|
||||
torch.cuda.synchronize()
|
||||
elapsed = time.time() - start_time
|
||||
print(f"[Timing] {video_length} frames ({latent_frames} latent) in {elapsed:.2f}s "
|
||||
f"({video_length / elapsed:.2f} frames/s)")
|
||||
if getattr(pipeline, "kv_cache_pos", None) is not None:
|
||||
kv_tokens = pipeline.kv_cache_pos[0]["k"].shape[1]
|
||||
kv_mib = sum(c["k"].numel() + c["v"].numel()
|
||||
for c in pipeline.kv_cache_pos + pipeline.kv_cache_neg) \
|
||||
* pipeline.kv_cache_pos[0]["k"].element_size() / (1024 ** 2)
|
||||
print(f"[KV cache] {kv_tokens} tokens per layer per branch, total {kv_mib:.1f} MiB (pos+neg, all layers)")
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
if video_length == 1:
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
|
||||
image = sample[0, :, 0]
|
||||
image = image.transpose(0, 1).transpose(1, 2)
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
else:
|
||||
save_results()
|
||||
@@ -0,0 +1,361 @@
|
||||
import os
|
||||
import sys
|
||||
import time
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoTokenizer,
|
||||
WanT5EncoderModel,
|
||||
WanTransformer3DModel_FlexForcing)
|
||||
from videox_fun.pipeline import WanFlexForcingPipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_video_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "model_full_load"
|
||||
# Multi GPUs config
|
||||
# Please ensure that the product of ulysses_degree and ring_degree equals the number of GPUs used.
|
||||
# For example, if you are using 8 GPUs, you can set ulysses_degree = 2 and ring_degree = 4.
|
||||
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = True
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with the fsdp_dit and sequential_cpu_offload.
|
||||
# [NOTE]: flex_attention block masks are rebuilt per partition, so compiling the
|
||||
# blocks only pays off when the partition is fixed - i.e. when `edit_span` and
|
||||
# `num_frame_per_block` stay the same across runs.
|
||||
compile_dit = False
|
||||
|
||||
# Config and model path
|
||||
config_path = "config/wan2.1/wan_civitai.yaml"
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/Wan2.1-T2V-1.3B"
|
||||
|
||||
# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
|
||||
sampler_name = "Flow"
|
||||
# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
|
||||
# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
|
||||
shift = 5
|
||||
|
||||
# Load pretrained model if need
|
||||
# Any Wan2.1 / CausVid / Self-Forcing checkpoint loads as-is: the Flex-Forcing
|
||||
# backbone inherits every parameter name and only the new `flex_kproj.*` tensors
|
||||
# are reported missing (they are identity-initialised, so step 0 is unchanged).
|
||||
transformer_path = "output_dir_wan2.1_flex_forcing_distill/checkpoint-1000/diffusion_pytorch_model.safetensors"
|
||||
vae_path = None
|
||||
lora_path = None
|
||||
|
||||
# Other params
|
||||
# The paper evaluates 5 s clips: 81 pixel frames = 21 latent frames at 832x432.
|
||||
sample_size = [432, 832]
|
||||
video_length = 81
|
||||
fps = 16
|
||||
|
||||
# --- 4.2 editing config ----------------------------------------------------
|
||||
# Clip to edit. Required: this script edits an existing clip and generates
|
||||
# nothing. predict_t2v.py writes to samples/wan-videos-flex-forcing-t2v/; any
|
||||
# other clip works too. It is resized / truncated to `sample_size` and
|
||||
# `video_length` below.
|
||||
input_video_path = "samples/wan-videos-flex-forcing-t2v/00000001.mp4"
|
||||
# Half-open range of **latent** frames to regenerate, e.g. (8, 15) for the
|
||||
# middle third of a 21-latent-frame clip. `None` edits the whole clip. A middle
|
||||
# span is the interesting case: it needs clean context from the future, which a
|
||||
# causal rollout does not have.
|
||||
edit_span = (8, 15)
|
||||
# How many *trailing* steps of the schedule to run. Keep it small - editing at a
|
||||
# planning timestep would restructure the clip instead of refining it. This is
|
||||
# the "restrict editing to low-level refinement timesteps" half of 4.2.
|
||||
edit_steps = 1
|
||||
# Granularity of the clean-context commit - the same uniform block size the
|
||||
# Self-Forcing rollout uses, and it does the same job here. `None` commits the
|
||||
# whole clip in one bidirectional pass; an int commits chunk by chunk in
|
||||
# temporal order, which bounds the peak memory of long clips. It also sizes the
|
||||
# transformer's per-block buffers: the block width becomes max(this, edit span
|
||||
# width). Match it to the block size the checkpoint was trained at unless memory
|
||||
# says otherwise.
|
||||
num_frame_per_block = 7
|
||||
|
||||
# --- Causal backbone (inherited from Self-Forcing) -------------------------
|
||||
# The noise level the clean context is committed at - the level the cache is
|
||||
# trained to be read back from.
|
||||
context_noise = 0.0
|
||||
# Local attention window size (-1 for global attention). Any-order editing
|
||||
# requires -1: the edited span must see clean tokens on both sides, which a
|
||||
# rolling window may already have evicted, and `edit_video` raises rather than
|
||||
# silently degrade. For long *generation* the paper uses a 21-latent-frame
|
||||
# window with a 3-frame sink (local_attn_size = 21, sink_size = 3), but that
|
||||
# combination cannot edit.
|
||||
local_attn_size = -1
|
||||
sink_size = 0
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# Some graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
prompt = "A stylish woman walks down a Tokyo street filled with warm glowing neon and animated city signage. She wears a black leather jacket, a long red dress, and black boots, and carries a black purse. She wears sunglasses and red lipstick. She walks confidently and casually. The street is damp and reflective, creating a mirror effect of the colorful lights. Many pedestrians walk about."
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
guidance_scale = 1.0
|
||||
seed = 43
|
||||
# The paper's 2-step DMD model denoises at [1000, 500]; 4 steps ([1000, 750,
|
||||
# 500, 250]) suit the CCD checkpoint. This is the schedule the refinement steps
|
||||
# are taken from: `edit_video` runs only its trailing `edit_steps`, so the
|
||||
# high-level planning timesteps stay untouched.
|
||||
num_inference_steps = 4
|
||||
lora_weight = 0.55
|
||||
save_path = "samples/wan-videos-flex-forcing-edit"
|
||||
|
||||
if not input_video_path or not os.path.isfile(input_video_path):
|
||||
raise FileNotFoundError(
|
||||
f"`input_video_path` must point at the clip to edit, got "
|
||||
f"{input_video_path!r}. This script only edits: generate one with "
|
||||
f"predict_t2v.py (it writes to samples/wan-videos-flex-forcing-t2v/) "
|
||||
f"or point at any clip of your own.")
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
config = OmegaConf.load(config_path)
|
||||
|
||||
# Load transformer with the Flex-Forcing backbone
|
||||
transformer_additional_kwargs = OmegaConf.to_container(config['transformer_additional_kwargs'])
|
||||
transformer_additional_kwargs['local_attn_size'] = local_attn_size
|
||||
transformer_additional_kwargs['sink_size'] = sink_size
|
||||
|
||||
transformer = WanTransformer3DModel_FlexForcing.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=transformer_additional_kwargs,
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
state_dict = state_dict["generator_ema"] if "generator_ema" in state_dict else state_dict
|
||||
state_dict = state_dict["generator"] if "generator" in state_dict else state_dict
|
||||
if any("._fsdp_wrapped_module." in k for k in state_dict.keys()):
|
||||
state_dict = {k.replace("model._fsdp_wrapped_module.", "model.", 1) if k.startswith("model._fsdp_wrapped_module.") else k: v for k, v in state_dict.items()}
|
||||
if any(k.startswith("model.") for k in state_dict.keys()):
|
||||
state_dict = {k.replace("model.", "", 1) if k.startswith("model.") else k: v for k, v in state_dict.items()}
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
# `flex_kproj.*` is expected to be missing when loading a Self-Forcing /
|
||||
# CausVid checkpoint that predates Flex-Forcing.
|
||||
other_missing = [k for k in m if "flex_kproj" not in k]
|
||||
print(f"missing keys: {len(m)} ({len(m) - len(other_missing)} of them flex_kproj), "
|
||||
f"unexpected keys: {len(u)}")
|
||||
|
||||
# Get Vae
|
||||
vae = AutoencoderKLWan.from_pretrained(
|
||||
os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
|
||||
additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Tokenizer
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
|
||||
)
|
||||
|
||||
# Get Text encoder
|
||||
text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
|
||||
additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
}[sampler_name]
|
||||
if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
|
||||
config['scheduler_kwargs']['shift'] = 1
|
||||
scheduler = Chosen_Scheduler(
|
||||
**filter_kwargs(Chosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
|
||||
)
|
||||
|
||||
# Get Pipeline
|
||||
pipeline = WanFlexForcingPipeline(
|
||||
transformer=transformer,
|
||||
vae=vae,
|
||||
tokenizer=tokenizer,
|
||||
text_encoder=text_encoder,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.blocks)):
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
print(f"[Flex-Forcing] local_attn_size={local_attn_size}, sink_size={sink_size}, "
|
||||
f"context_noise={context_noise}")
|
||||
print(f"[Flex-Forcing 4.2] edit_span={edit_span} latent frames, edit_steps={edit_steps} "
|
||||
f"of {num_inference_steps}, num_frame_per_block={num_frame_per_block}")
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
with torch.no_grad():
|
||||
video_length = int((video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
|
||||
latent_frames = (video_length - 1) // vae.config.temporal_compression_ratio + 1
|
||||
# Printed before anything expensive runs: `edit_span` is in *latent* frames,
|
||||
# so this is where a span that does not fit the clip shows up.
|
||||
print(f"[Flex-Forcing 4.2] {input_video_path}: {video_length} pixel frames "
|
||||
f"= {latent_frames} latent frames")
|
||||
|
||||
# 1. The clip to edit, [B, C, F, H, W] in [0, 1] - the range
|
||||
# `decode_latents` returns, so a clip from predict_t2v.py goes straight
|
||||
# back in.
|
||||
video, _, _, _ = get_video_to_video_latent(
|
||||
input_video_path, video_length, sample_size, fps=fps)
|
||||
source = video.to(device=device, dtype=weight_dtype)
|
||||
|
||||
# 2. Edit one span at the refinement timesteps only, conditioning on the
|
||||
# clean context of the whole clip - past and future alike.
|
||||
torch.cuda.synchronize()
|
||||
start_time = time.time()
|
||||
sample = pipeline.edit_video(
|
||||
prompt = prompt,
|
||||
video = source,
|
||||
edit_span = edit_span,
|
||||
negative_prompt = negative_prompt,
|
||||
guidance_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
edit_steps = edit_steps,
|
||||
shift = shift,
|
||||
context_noise = context_noise,
|
||||
num_frame_per_block = num_frame_per_block,
|
||||
generator = generator,
|
||||
).videos
|
||||
torch.cuda.synchronize()
|
||||
elapsed = time.time() - start_time
|
||||
print(f"[Timing] edited span {edit_span} in {elapsed:.2f}s")
|
||||
# Same diagnostic as predict_t2v.py, read after the edit: the cache now holds
|
||||
# the whole clip committed as clean context, so `kv_tokens` is the full-clip
|
||||
# width the edited span was able to attend over.
|
||||
if getattr(pipeline, "kv_cache_pos", None) is not None:
|
||||
kv_tokens = pipeline.kv_cache_pos[0]["k"].shape[1]
|
||||
kv_mib = sum(c["k"].numel() + c["v"].numel()
|
||||
for c in pipeline.kv_cache_pos + pipeline.kv_cache_neg) \
|
||||
* pipeline.kv_cache_pos[0]["k"].element_size() / (1024 ** 2)
|
||||
print(f"[KV cache] {kv_tokens} tokens per layer per branch, total {kv_mib:.1f} MiB (pos+neg, all layers)")
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
if video_length == 1:
|
||||
image_path = os.path.join(save_path, prefix + ".png")
|
||||
|
||||
image = sample[0, :, 0]
|
||||
image = image.transpose(0, 1).transpose(1, 2)
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(image_path)
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + "-edited.mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
# Keep the source next to the edit, and re-encoded through the same VAE
|
||||
# round trip, so the untouched frames and the refined span compare like
|
||||
# for like rather than against the original file.
|
||||
save_videos_grid(source, os.path.join(save_path, prefix + "-source.mp4"), fps=fps)
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
else:
|
||||
save_results()
|
||||
@@ -142,7 +142,7 @@ transformer = Wan2_2Transformer3DModel_Animate.from_pretrained(
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
if config['transformer_additional_kwargs'].get('transformer_combination_type', 'single') == "moe":
|
||||
transformer_2 = Wan2_2Transformer3DModel.from_pretrained(
|
||||
transformer_2 = Wan2_2Transformer3DModel_Animate.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_high_noise_model_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
|
||||
@@ -147,7 +147,7 @@ transformer = Wan2_2Transformer3DModel_S2V.from_pretrained(
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
if config['transformer_additional_kwargs'].get('transformer_combination_type', 'single') == "moe":
|
||||
transformer_2 = Wan2_2Transformer3DModel.from_pretrained(
|
||||
transformer_2 = Wan2_2Transformer3DModel_S2V.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_high_noise_model_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
|
||||
@@ -0,0 +1,384 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8, AutoencoderTinyWan,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2TI2VPipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "sequential_cpu_offload"
|
||||
# Multi GPUs config
|
||||
# Please ensure that the product of ulysses_degree and ring_degree equals the number of GPUs used.
|
||||
# For example, if you are using 8 GPUs, you can set ulysses_degree = 2 and ring_degree = 4.
|
||||
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = True
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with the fsdp_dit and sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# TeaCache config
|
||||
enable_teacache = True
|
||||
# Recommended to be set between 0.05 and 0.30. A larger threshold can cache more steps, speeding up the inference process,
|
||||
# but it may cause slight differences between the generated content and the original content.
|
||||
# # --------------------------------------------------------------------------------------------------- #
|
||||
# | Model Name | threshold | Model Name | threshold |
|
||||
# | Wan2.2-T2V-A14B | 0.10~0.15 | Wan2.2-I2V-A14B | 0.15~0.20 |
|
||||
# # --------------------------------------------------------------------------------------------------- #
|
||||
teacache_threshold = 0.10
|
||||
# The number of steps to skip TeaCache at the beginning of the inference process, which can
|
||||
# reduce the impact of TeaCache on generated video quality.
|
||||
num_skip_start_steps = 5
|
||||
# Whether to offload TeaCache tensors to cpu to save a little bit of GPU memory.
|
||||
teacache_offload = False
|
||||
|
||||
# Skip some cfg steps in inference
|
||||
# Recommended to be set between 0.00 and 0.25
|
||||
cfg_skip_ratio = 0
|
||||
|
||||
# Riflex config
|
||||
enable_riflex = False
|
||||
# Index of intrinsic frequency
|
||||
riflex_k = 6
|
||||
|
||||
# Config and model path
|
||||
config_path = "config/wan2.2/wan_civitai_5b.yaml"
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/Wan2.2-TI2V-5B"
|
||||
|
||||
# TAE (Tiny AutoEncoder): shares the Wan2.2 VAE latent space but decodes much
|
||||
# cheaper (<0.5GB vs ~6-9GB), at the cost of fine detail. Weights: taew2_2.safetensors.
|
||||
tae_path = "models/Diffusion_Transformer/taew2_2.safetensors"
|
||||
|
||||
# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
|
||||
sampler_name = "Flow_Unipc"
|
||||
# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
|
||||
# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
|
||||
shift = 5
|
||||
|
||||
# Load pretrained model if need
|
||||
# The transformer_path is used for low noise model, the transformer_high_path is used for high noise model.
|
||||
# Since Wan2.2-5b consists of only one model, only transformer_path is used.
|
||||
transformer_path = None
|
||||
transformer_high_path = None
|
||||
vae_path = None
|
||||
# Load lora model if need
|
||||
# The lora_path is used for low noise model, the lora_high_path is used for high noise model.
|
||||
# Since Wan2.2-5b consists of only one model, only lora_path is used.
|
||||
lora_path = None
|
||||
lora_high_path = None
|
||||
|
||||
# Other params
|
||||
sample_size = [704, 1280]
|
||||
video_length = 81
|
||||
fps = 24
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
|
||||
# prompts
|
||||
prompt = "一只棕色的狗摇着头,坐在舒适房间里的浅色沙发上。在狗的后面,架子上有一幅镶框的画,周围是粉红色的花朵。房间里柔和温暖的灯光营造出舒适的氛围。"
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
guidance_scale = 6.0
|
||||
seed = 43
|
||||
num_inference_steps = 50
|
||||
# The lora_weight is used for low noise model, the lora_high_weight is used for high noise model.
|
||||
lora_weight = 0.55
|
||||
lora_high_weight = 0.55
|
||||
save_path = "samples/wan-videos-ti2v-tae"
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
config = OmegaConf.load(config_path)
|
||||
# Override the VAE with AutoencoderTinyWan (TAE); everything else (latent
|
||||
# channels, patch size, compression ratios) is inferred from the weight file.
|
||||
config['vae_kwargs'] = OmegaConf.create({
|
||||
'vae_type': 'AutoencoderTinyWan',
|
||||
'vae_subpath': tae_path,
|
||||
})
|
||||
boundary = config['transformer_additional_kwargs'].get('boundary', 0.875)
|
||||
|
||||
transformer = Wan2_2Transformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_low_noise_model_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
if config['transformer_additional_kwargs'].get('transformer_combination_type', 'single') == "moe":
|
||||
transformer_2 = Wan2_2Transformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_high_noise_model_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
else:
|
||||
transformer_2 = None
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer_2.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Vae
|
||||
Chosen_AutoencoderKL = {
|
||||
"AutoencoderKLWan": AutoencoderKLWan,
|
||||
"AutoencoderKLWan3_8": AutoencoderKLWan3_8,
|
||||
"AutoencoderTinyWan": AutoencoderTinyWan
|
||||
}[config['vae_kwargs'].get('vae_type', 'AutoencoderKLWan')]
|
||||
vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
|
||||
additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
if isinstance(vae, AutoencoderTinyWan):
|
||||
# TAE checkpoints use bare "encoder.*" / "decoder.*" keys, which live
|
||||
# under vae.model in the AutoencoderTinyWan wrapper.
|
||||
state_dict = vae.model.patch_tgrow_layers(state_dict)
|
||||
m, u = vae.model.load_state_dict(state_dict, strict=False)
|
||||
else:
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Tokenizer
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
|
||||
)
|
||||
|
||||
# Get Text encoder
|
||||
text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
|
||||
additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
}[sampler_name]
|
||||
if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
|
||||
config['scheduler_kwargs']['shift'] = 1
|
||||
scheduler = Chosen_Scheduler(
|
||||
**filter_kwargs(Chosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
|
||||
)
|
||||
|
||||
# Get Pipeline
|
||||
pipeline = Wan2_2TI2VPipeline(
|
||||
transformer=transformer,
|
||||
transformer_2=transformer_2,
|
||||
vae=vae,
|
||||
tokenizer=tokenizer,
|
||||
text_encoder=text_encoder,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if transformer_2 is not None:
|
||||
transformer_2.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2 = shard_fn(pipeline.transformer_2)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.blocks)):
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
if transformer_2 is not None:
|
||||
for i in range(len(pipeline.transformer_2.blocks)):
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
|
||||
pipeline.transformer.enable_teacache(
|
||||
coefficients, num_inference_steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
|
||||
)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.share_teacache(transformer=pipeline.transformer)
|
||||
|
||||
if cfg_skip_ratio is not None:
|
||||
print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
|
||||
pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, num_inference_steps)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.share_cfg_skip(transformer=pipeline.transformer)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
if lora_high_path is not None and transformer_2 is not None:
|
||||
pipeline = merge_lora(pipeline, lora_high_path, lora_high_weight, device=device, dtype=weight_dtype, sub_transformer_name="transformer_2")
|
||||
|
||||
with torch.no_grad():
|
||||
video_length = int((video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
|
||||
latent_frames = (video_length - 1) // vae.config.temporal_compression_ratio + 1
|
||||
|
||||
if enable_riflex:
|
||||
pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.enable_riflex(k = riflex_k, L_test = latent_frames)
|
||||
|
||||
if validation_image_start is not None:
|
||||
input_video, input_video_mask, clip_image = get_image_to_video_latent(validation_image_start, None, video_length=video_length, sample_size=sample_size)
|
||||
else:
|
||||
input_video, input_video_mask, clip_image = None, None, None
|
||||
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
num_frames = video_length,
|
||||
negative_prompt = negative_prompt,
|
||||
height = sample_size[0],
|
||||
width = sample_size[1],
|
||||
generator = generator,
|
||||
guidance_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
boundary = boundary,
|
||||
|
||||
video = input_video,
|
||||
mask_video = input_video_mask,
|
||||
shift = shift,
|
||||
).videos
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
if lora_high_path is not None and transformer_2 is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_high_path, lora_high_weight, device=device, dtype=weight_dtype, sub_transformer_name="transformer_2")
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
if video_length == 1:
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
|
||||
image = sample[0, :, 0]
|
||||
image = image.transpose(0, 1).transpose(1, 2)
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
else:
|
||||
save_results()
|
||||
@@ -0,0 +1,415 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, CLIPModel,
|
||||
Wan2_2Transformer3DModel,
|
||||
WanLatentUpsamplerModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2FunInpaintPipeline, WanLatentUpsamplePipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "sequential_cpu_offload"
|
||||
# Multi GPUs config
|
||||
# Please ensure that the product of ulysses_degree and ring_degree equals the number of GPUs used.
|
||||
# For example, if you are using 8 GPUs, you can set ulysses_degree = 2 and ring_degree = 4.
|
||||
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = True
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with the fsdp_dit and sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# TeaCache config
|
||||
enable_teacache = True
|
||||
# Recommended to be set between 0.05 and 0.30. A larger threshold can cache more steps, speeding up the inference process,
|
||||
# but it may cause slight differences between the generated content and the original content.
|
||||
teacache_threshold = 0.10
|
||||
# The number of steps to skip TeaCache at the beginning of the inference process, which can
|
||||
# reduce the impact of TeaCache on generated video quality.
|
||||
num_skip_start_steps = 5
|
||||
# Whether to offload TeaCache tensors to cpu to save a little bit of GPU memory.
|
||||
teacache_offload = False
|
||||
|
||||
# Skip some cfg steps in inference
|
||||
# Recommended to be set between 0.00 and 0.25
|
||||
cfg_skip_ratio = 0
|
||||
|
||||
# Riflex config
|
||||
enable_riflex = False
|
||||
# Index of intrinsic frequency
|
||||
riflex_k = 6
|
||||
|
||||
# Config and model path
|
||||
config_path = "config/wan2.2/wan_civitai_i2v_2.2vae.yaml"
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/Wan2.2-Fun-I2V-A14B-2.2VAE"
|
||||
|
||||
# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
|
||||
sampler_name = "Flow"
|
||||
# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
|
||||
# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
|
||||
shift = 5
|
||||
|
||||
# Latent upsampler config
|
||||
# The latent upsampler spatially upsamples the generated latents before VAE decoding.
|
||||
enable_latent_upsample = True
|
||||
|
||||
# Load pretrained model if need
|
||||
# The transformer_path is used for low noise model, the transformer_high_path is used for high noise model.
|
||||
transformer_path = None
|
||||
transformer_high_path = None
|
||||
vae_path = None
|
||||
# Load pretrained latent upsampler model if need.
|
||||
# If latent_upsampler_path is None, the latent_upsampler_subpath subfolder of model_name will be used.
|
||||
latent_upsampler_path = None
|
||||
# Load lora model if need
|
||||
# The lora_path is used for low noise model, the lora_high_path is used for high noise model.
|
||||
lora_path = None
|
||||
lora_high_path = None
|
||||
|
||||
# Other params
|
||||
sample_size = [704, 1280]
|
||||
video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
validation_image_end = None
|
||||
|
||||
# 使用更长的neg prompt如"模糊,突变,变形,失真,画面暗,文本字幕,画面固定,连环画,漫画,线稿,没有主体。",可以增加稳定性
|
||||
# 在neg prompt中添加"安静,固定"等词语可以增加动态性。
|
||||
prompt = "一只棕色的狗摇着头,坐在舒适房间里的浅色沙发上。在狗的后面,架子上有一幅镶框的画,周围是粉红色的花朵。房间里柔和温暖的灯光营造出舒适的氛围。"
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
guidance_scale = 6.0
|
||||
seed = 43
|
||||
num_inference_steps = 50
|
||||
# The lora_weight is used for low noise model, the lora_high_weight is used for high noise model.
|
||||
lora_weight = 0.55
|
||||
lora_high_weight = 0.55
|
||||
save_path = "samples/wan-videos-fun-i2v-2.2vae"
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
config = OmegaConf.load(config_path)
|
||||
boundary = config['transformer_additional_kwargs'].get('boundary', 0.900)
|
||||
|
||||
transformer = Wan2_2Transformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_low_noise_model_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
if config['transformer_additional_kwargs'].get('transformer_combination_type', 'single') == "moe":
|
||||
transformer_2 = Wan2_2Transformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_high_noise_model_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
else:
|
||||
transformer_2 = None
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer_2.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Vae
|
||||
Chosen_AutoencoderKL = {
|
||||
"AutoencoderKLWan": AutoencoderKLWan,
|
||||
"AutoencoderKLWan3_8": AutoencoderKLWan3_8
|
||||
}[config['vae_kwargs'].get('vae_type', 'AutoencoderKLWan')]
|
||||
vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
|
||||
additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Tokenizer
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
|
||||
)
|
||||
|
||||
# Get Text encoder
|
||||
text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
|
||||
additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
}[sampler_name]
|
||||
if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
|
||||
config['scheduler_kwargs']['shift'] = 1
|
||||
scheduler = Chosen_Scheduler(
|
||||
**filter_kwargs(Chosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
|
||||
)
|
||||
|
||||
# Get Pipeline
|
||||
pipeline = Wan2_2FunInpaintPipeline(
|
||||
transformer=transformer,
|
||||
transformer_2=transformer_2,
|
||||
vae=vae,
|
||||
tokenizer=tokenizer,
|
||||
text_encoder=text_encoder,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if transformer_2 is not None:
|
||||
transformer_2.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2 = shard_fn(pipeline.transformer_2)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.blocks)):
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
if transformer_2 is not None:
|
||||
for i in range(len(pipeline.transformer_2.blocks)):
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
|
||||
pipeline.transformer.enable_teacache(
|
||||
coefficients, num_inference_steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
|
||||
)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.share_teacache(transformer=pipeline.transformer)
|
||||
|
||||
if cfg_skip_ratio is not None:
|
||||
print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
|
||||
pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, num_inference_steps)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.share_cfg_skip(transformer=pipeline.transformer)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
if lora_high_path is not None and transformer_2 is not None:
|
||||
pipeline = merge_lora(pipeline, lora_high_path, lora_high_weight, device=device, dtype=weight_dtype, sub_transformer_name="transformer_2")
|
||||
|
||||
with torch.no_grad():
|
||||
video_length = int((video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
|
||||
latent_frames = (video_length - 1) // vae.config.temporal_compression_ratio + 1
|
||||
|
||||
if enable_riflex:
|
||||
pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.enable_riflex(k = riflex_k, L_test = latent_frames)
|
||||
|
||||
input_video, input_video_mask, clip_image = get_image_to_video_latent(validation_image_start, validation_image_end, video_length=video_length, sample_size=sample_size)
|
||||
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
num_frames = video_length,
|
||||
negative_prompt = negative_prompt,
|
||||
height = sample_size[0],
|
||||
width = sample_size[1],
|
||||
generator = generator,
|
||||
guidance_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
boundary = boundary,
|
||||
|
||||
video = input_video,
|
||||
mask_video = input_video_mask,
|
||||
shift = shift,
|
||||
output_type = "latent" if enable_latent_upsample else "pil",
|
||||
).videos
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
if lora_high_path is not None and transformer_2 is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_high_path, lora_high_weight, device=device, dtype=weight_dtype, sub_transformer_name="transformer_2")
|
||||
|
||||
if enable_latent_upsample:
|
||||
lu_kwargs = OmegaConf.to_container(config['latent_upsampler_kwargs'], resolve=True)
|
||||
lu_subpath = lu_kwargs.pop('latent_upsampler_subpath', 'latent_upsampler')
|
||||
|
||||
if latent_upsampler_path is None:
|
||||
latent_upsampler_path = os.path.join(model_name, lu_subpath)
|
||||
print(f"From latent_upsampler checkpoint: {latent_upsampler_path}")
|
||||
|
||||
if os.path.isdir(latent_upsampler_path):
|
||||
latent_upsampler = WanLatentUpsamplerModel.from_pretrained(
|
||||
latent_upsampler_path,
|
||||
in_channels=vae.config.latent_channels,
|
||||
**lu_kwargs,
|
||||
)
|
||||
else:
|
||||
latent_upsampler = WanLatentUpsamplerModel(
|
||||
in_channels=vae.config.latent_channels,
|
||||
**lu_kwargs,
|
||||
)
|
||||
if latent_upsampler_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
state_dict = load_file(latent_upsampler_path)
|
||||
else:
|
||||
state_dict = torch.load(latent_upsampler_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = latent_upsampler.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
latent_upsampler.eval().to(device, dtype=weight_dtype)
|
||||
|
||||
upsample_pipeline = WanLatentUpsamplePipeline(
|
||||
vae=pipeline.vae,
|
||||
latent_upsampler=latent_upsampler,
|
||||
)
|
||||
upsample_pipeline.to(device=device, dtype=weight_dtype)
|
||||
|
||||
with torch.no_grad():
|
||||
upsampled = upsample_pipeline(
|
||||
latents=sample,
|
||||
output_type="pt",
|
||||
return_dict=False,
|
||||
)
|
||||
sample = upsampled[0]
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
if video_length == 1:
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
|
||||
image = sample[0, :, 0]
|
||||
image = image.transpose(0, 1).transpose(1, 2)
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
else:
|
||||
save_results()
|
||||
@@ -0,0 +1,429 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8, AutoencoderTinyWan,
|
||||
AutoTokenizer, CLIPModel,
|
||||
Wan2_2Transformer3DModel,
|
||||
WanLatentUpsamplerModel, WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2FunInpaintPipeline, WanLatentUpsamplePipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "sequential_cpu_offload"
|
||||
# Multi GPUs config
|
||||
# Please ensure that the product of ulysses_degree and ring_degree equals the number of GPUs used.
|
||||
# For example, if you are using 8 GPUs, you can set ulysses_degree = 2 and ring_degree = 4.
|
||||
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = True
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with the fsdp_dit and sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# TeaCache config
|
||||
enable_teacache = True
|
||||
# Recommended to be set between 0.05 and 0.30. A larger threshold can cache more steps, speeding up the inference process,
|
||||
# but it may cause slight differences between the generated content and the original content.
|
||||
teacache_threshold = 0.10
|
||||
# The number of steps to skip TeaCache at the beginning of the inference process, which can
|
||||
# reduce the impact of TeaCache on generated video quality.
|
||||
num_skip_start_steps = 5
|
||||
# Whether to offload TeaCache tensors to cpu to save a little bit of GPU memory.
|
||||
teacache_offload = False
|
||||
|
||||
# Skip some cfg steps in inference
|
||||
# Recommended to be set between 0.00 and 0.25
|
||||
cfg_skip_ratio = 0
|
||||
|
||||
# Riflex config
|
||||
enable_riflex = False
|
||||
# Index of intrinsic frequency
|
||||
riflex_k = 6
|
||||
|
||||
# Config and model path
|
||||
config_path = "config/wan2.2/wan_civitai_i2v_2.2vae.yaml"
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/Wan2.2-Fun-I2V-A14B-2.2VAE"
|
||||
# TAE (Tiny AutoEncoder): shares the Wan2.2 VAE latent space but decodes much
|
||||
# cheaper (<0.5GB vs ~6-9GB), at the cost of fine detail. Weights: taew2_2.safetensors.
|
||||
tae_path = "models/Diffusion_Transformer/taew2_2.safetensors"
|
||||
|
||||
# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
|
||||
sampler_name = "Flow"
|
||||
# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
|
||||
# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
|
||||
shift = 5
|
||||
|
||||
# Latent upsampler config
|
||||
# The latent upsampler spatially upsamples the generated latents before VAE decoding.
|
||||
enable_latent_upsample = True
|
||||
|
||||
# Load pretrained model if need
|
||||
# The transformer_path is used for low noise model, the transformer_high_path is used for high noise model.
|
||||
transformer_path = None
|
||||
transformer_high_path = None
|
||||
vae_path = None
|
||||
# Load pretrained latent upsampler model if need.
|
||||
# If latent_upsampler_path is None, the latent_upsampler_subpath subfolder of model_name will be used.
|
||||
latent_upsampler_path = None
|
||||
# Load lora model if need
|
||||
# The lora_path is used for low noise model, the lora_high_path is used for high noise model.
|
||||
lora_path = None
|
||||
lora_high_path = None
|
||||
|
||||
# Other params
|
||||
sample_size = [704, 1280]
|
||||
video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# If you want to generate from text, please set the validation_image_start = None and validation_image_end = None
|
||||
validation_image_start = "asset/1.png"
|
||||
validation_image_end = None
|
||||
|
||||
# 使用更长的neg prompt如"模糊,突变,变形,失真,画面暗,文本字幕,画面固定,连环画,漫画,线稿,没有主体。",可以增加稳定性
|
||||
# 在neg prompt中添加"安静,固定"等词语可以增加动态性。
|
||||
prompt = "一只棕色的狗摇着头,坐在舒适房间里的浅色沙发上。在狗的后面,架子上有一幅镶框的画,周围是粉红色的花朵。房间里柔和温暖的灯光营造出舒适的氛围。"
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
guidance_scale = 6.0
|
||||
seed = 43
|
||||
num_inference_steps = 50
|
||||
# The lora_weight is used for low noise model, the lora_high_weight is used for high noise model.
|
||||
lora_weight = 0.55
|
||||
lora_high_weight = 0.55
|
||||
save_path = "samples/wan-videos-fun-i2v-2.2vae-tae"
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
config = OmegaConf.load(config_path)
|
||||
# Override the VAE with AutoencoderTinyWan (TAE); everything else (latent
|
||||
# channels, patch size, compression ratios) is inferred from the weight file.
|
||||
config['vae_kwargs'] = OmegaConf.create({
|
||||
'vae_type': 'AutoencoderTinyWan',
|
||||
'vae_subpath': tae_path,
|
||||
})
|
||||
boundary = config['transformer_additional_kwargs'].get('boundary', 0.900)
|
||||
|
||||
transformer = Wan2_2Transformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_low_noise_model_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
if config['transformer_additional_kwargs'].get('transformer_combination_type', 'single') == "moe":
|
||||
transformer_2 = Wan2_2Transformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_high_noise_model_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
else:
|
||||
transformer_2 = None
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer_2.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Vae
|
||||
Chosen_AutoencoderKL = {
|
||||
"AutoencoderKLWan": AutoencoderKLWan,
|
||||
"AutoencoderKLWan3_8": AutoencoderKLWan3_8,
|
||||
"AutoencoderTinyWan": AutoencoderTinyWan
|
||||
}[config['vae_kwargs'].get('vae_type', 'AutoencoderKLWan')]
|
||||
vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
|
||||
additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
if isinstance(vae, AutoencoderTinyWan):
|
||||
state_dict = vae.model.patch_tgrow_layers(state_dict)
|
||||
m, u = vae.model.load_state_dict(state_dict, strict=False)
|
||||
else:
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Tokenizer
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
|
||||
)
|
||||
|
||||
# Get Text encoder
|
||||
text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
|
||||
additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
}[sampler_name]
|
||||
if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
|
||||
config['scheduler_kwargs']['shift'] = 1
|
||||
scheduler = Chosen_Scheduler(
|
||||
**filter_kwargs(Chosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
|
||||
)
|
||||
|
||||
# Get Pipeline
|
||||
pipeline = Wan2_2FunInpaintPipeline(
|
||||
transformer=transformer,
|
||||
transformer_2=transformer_2,
|
||||
vae=vae,
|
||||
tokenizer=tokenizer,
|
||||
text_encoder=text_encoder,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if transformer_2 is not None:
|
||||
transformer_2.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2 = shard_fn(pipeline.transformer_2)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.blocks)):
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
if transformer_2 is not None:
|
||||
for i in range(len(pipeline.transformer_2.blocks)):
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
|
||||
pipeline.transformer.enable_teacache(
|
||||
coefficients, num_inference_steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
|
||||
)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.share_teacache(transformer=pipeline.transformer)
|
||||
|
||||
if cfg_skip_ratio is not None:
|
||||
print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
|
||||
pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, num_inference_steps)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.share_cfg_skip(transformer=pipeline.transformer)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
if lora_high_path is not None and transformer_2 is not None:
|
||||
pipeline = merge_lora(pipeline, lora_high_path, lora_high_weight, device=device, dtype=weight_dtype, sub_transformer_name="transformer_2")
|
||||
|
||||
with torch.no_grad():
|
||||
video_length = int((video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
|
||||
latent_frames = (video_length - 1) // vae.config.temporal_compression_ratio + 1
|
||||
|
||||
if enable_riflex:
|
||||
pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.enable_riflex(k = riflex_k, L_test = latent_frames)
|
||||
|
||||
input_video, input_video_mask, clip_image = get_image_to_video_latent(validation_image_start, validation_image_end, video_length=video_length, sample_size=sample_size)
|
||||
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
num_frames = video_length,
|
||||
negative_prompt = negative_prompt,
|
||||
height = sample_size[0],
|
||||
width = sample_size[1],
|
||||
generator = generator,
|
||||
guidance_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
boundary = boundary,
|
||||
|
||||
video = input_video,
|
||||
mask_video = input_video_mask,
|
||||
shift = shift,
|
||||
output_type = "latent" if enable_latent_upsample else "pil",
|
||||
).videos
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
if lora_high_path is not None and transformer_2 is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_high_path, lora_high_weight, device=device, dtype=weight_dtype, sub_transformer_name="transformer_2")
|
||||
|
||||
if enable_latent_upsample:
|
||||
lu_kwargs = OmegaConf.to_container(config['latent_upsampler_kwargs'], resolve=True)
|
||||
lu_subpath = lu_kwargs.pop('latent_upsampler_subpath', 'latent_upsampler')
|
||||
|
||||
if latent_upsampler_path is None:
|
||||
latent_upsampler_path = os.path.join(model_name, lu_subpath)
|
||||
print(f"From latent_upsampler checkpoint: {latent_upsampler_path}")
|
||||
|
||||
if os.path.isdir(latent_upsampler_path):
|
||||
latent_upsampler = WanLatentUpsamplerModel.from_pretrained(
|
||||
latent_upsampler_path,
|
||||
in_channels=vae.config.latent_channels,
|
||||
**lu_kwargs,
|
||||
)
|
||||
else:
|
||||
latent_upsampler = WanLatentUpsamplerModel(
|
||||
in_channels=vae.config.latent_channels,
|
||||
**lu_kwargs,
|
||||
)
|
||||
if latent_upsampler_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
state_dict = load_file(latent_upsampler_path)
|
||||
else:
|
||||
state_dict = torch.load(latent_upsampler_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = latent_upsampler.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
latent_upsampler.eval().to(device, dtype=weight_dtype)
|
||||
|
||||
upsample_pipeline = WanLatentUpsamplePipeline(
|
||||
vae=pipeline.vae,
|
||||
latent_upsampler=latent_upsampler,
|
||||
)
|
||||
upsample_pipeline.to(device=device, dtype=weight_dtype)
|
||||
|
||||
with torch.no_grad():
|
||||
upsampled = upsample_pipeline(
|
||||
latents=sample,
|
||||
output_type="pt",
|
||||
return_dict=False,
|
||||
)
|
||||
sample = upsampled[0]
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
if video_length == 1:
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
|
||||
image = sample[0, :, 0]
|
||||
image = image.transpose(0, 1).transpose(1, 2)
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
else:
|
||||
save_results()
|
||||
@@ -0,0 +1,406 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel,
|
||||
WanLatentUpsamplerModel,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2Pipeline, WanLatentUpsamplePipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "sequential_cpu_offload"
|
||||
# Multi GPUs config
|
||||
# Please ensure that the product of ulysses_degree and ring_degree equals the number of GPUs used.
|
||||
# For example, if you are using 8 GPUs, you can set ulysses_degree = 2 and ring_degree = 4.
|
||||
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = True
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with the fsdp_dit and sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# TeaCache config
|
||||
enable_teacache = True
|
||||
# Recommended to be set between 0.05 and 0.30. A larger threshold can cache more steps, speeding up the inference process,
|
||||
# but it may cause slight differences between the generated content and the original content.
|
||||
teacache_threshold = 0.10
|
||||
# The number of steps to skip TeaCache at the beginning of the inference process, which can
|
||||
# reduce the impact of TeaCache on generated video quality.
|
||||
num_skip_start_steps = 5
|
||||
# Whether to offload TeaCache tensors to cpu to save a little bit of GPU memory.
|
||||
teacache_offload = False
|
||||
|
||||
# Skip some cfg steps in inference
|
||||
# Recommended to be set between 0.00 and 0.25
|
||||
cfg_skip_ratio = 0
|
||||
|
||||
# Riflex config
|
||||
enable_riflex = False
|
||||
# Index of intrinsic frequency
|
||||
riflex_k = 6
|
||||
|
||||
# Config and model path
|
||||
config_path = "config/wan2.2/wan_civitai_t2v_2.2vae.yaml"
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/Wan2.2-Fun-T2V-A14B-2.2VAE"
|
||||
|
||||
# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
|
||||
sampler_name = "Flow"
|
||||
# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
|
||||
# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
|
||||
shift = 5
|
||||
|
||||
# Latent upsampler config
|
||||
# The latent upsampler spatially upsamples the generated latents before VAE decoding.
|
||||
enable_latent_upsample = True
|
||||
|
||||
# Load pretrained model if need
|
||||
# The transformer_path is used for low noise model, the transformer_high_path is used for high noise model.
|
||||
transformer_path = None
|
||||
transformer_high_path = None
|
||||
vae_path = None
|
||||
# Load pretrained latent upsampler model if need.
|
||||
# If latent_upsampler_path is None, the latent_upsampler_subpath subfolder of model_name will be used.
|
||||
latent_upsampler_path = None
|
||||
# Load lora model if need
|
||||
# The lora_path is used for low noise model, the lora_high_path is used for high noise model.
|
||||
lora_path = None
|
||||
lora_high_path = None
|
||||
|
||||
# Other params
|
||||
sample_size = [480, 832]
|
||||
video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# 使用更长的neg prompt如"模糊,突变,变形,失真,画面暗,文本字幕,画面固定,连环画,漫画,线稿,没有主体。",可以增加稳定性
|
||||
# 在neg prompt中添加"安静,固定"等词语可以增加动态性。
|
||||
prompt = "一只棕色的狗摇着头,坐在舒适房间里的浅色沙发上。在狗的后面,架子上有一幅镶框的画,周围是粉红色的花朵。房间里柔和温暖的灯光营造出舒适的氛围。"
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
guidance_scale = 6.0
|
||||
seed = 43
|
||||
num_inference_steps = 50
|
||||
# The lora_weight is used for low noise model, the lora_high_weight is used for high noise model.
|
||||
lora_weight = 0.55
|
||||
lora_high_weight = 0.55
|
||||
save_path = "samples/wan-videos-fun-t2v-2.2vae"
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
config = OmegaConf.load(config_path)
|
||||
boundary = config['transformer_additional_kwargs'].get('boundary', 0.900)
|
||||
|
||||
transformer = Wan2_2Transformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_low_noise_model_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
if config['transformer_additional_kwargs'].get('transformer_combination_type', 'single') == "moe":
|
||||
transformer_2 = Wan2_2Transformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_high_noise_model_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
else:
|
||||
transformer_2 = None
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer_2.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Vae
|
||||
Chosen_AutoencoderKL = {
|
||||
"AutoencoderKLWan": AutoencoderKLWan,
|
||||
"AutoencoderKLWan3_8": AutoencoderKLWan3_8
|
||||
}[config['vae_kwargs'].get('vae_type', 'AutoencoderKLWan')]
|
||||
vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
|
||||
additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Tokenizer
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
|
||||
)
|
||||
|
||||
# Get Text encoder
|
||||
text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
|
||||
additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
}[sampler_name]
|
||||
if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
|
||||
config['scheduler_kwargs']['shift'] = 1
|
||||
scheduler = Chosen_Scheduler(
|
||||
**filter_kwargs(Chosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
|
||||
)
|
||||
|
||||
# Get Pipeline
|
||||
pipeline = Wan2_2Pipeline(
|
||||
transformer=transformer,
|
||||
transformer_2=transformer_2,
|
||||
vae=vae,
|
||||
tokenizer=tokenizer,
|
||||
text_encoder=text_encoder,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if transformer_2 is not None:
|
||||
transformer_2.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2 = shard_fn(pipeline.transformer_2)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.blocks)):
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
if transformer_2 is not None:
|
||||
for i in range(len(pipeline.transformer_2.blocks)):
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
|
||||
pipeline.transformer.enable_teacache(
|
||||
coefficients, num_inference_steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
|
||||
)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.share_teacache(transformer=pipeline.transformer)
|
||||
|
||||
if cfg_skip_ratio is not None:
|
||||
print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
|
||||
pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, num_inference_steps)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.share_cfg_skip(transformer=pipeline.transformer)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
if lora_high_path is not None and transformer_2 is not None:
|
||||
pipeline = merge_lora(pipeline, lora_high_path, lora_high_weight, device=device, dtype=weight_dtype, sub_transformer_name="transformer_2")
|
||||
|
||||
with torch.no_grad():
|
||||
video_length = int((video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
|
||||
latent_frames = (video_length - 1) // vae.config.temporal_compression_ratio + 1
|
||||
|
||||
if enable_riflex:
|
||||
pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.enable_riflex(k = riflex_k, L_test = latent_frames)
|
||||
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
num_frames = video_length,
|
||||
negative_prompt = negative_prompt,
|
||||
height = sample_size[0],
|
||||
width = sample_size[1],
|
||||
generator = generator,
|
||||
guidance_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
boundary = boundary,
|
||||
shift = shift,
|
||||
output_type = "latent" if enable_latent_upsample else "pil",
|
||||
).videos
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
if lora_high_path is not None and transformer_2 is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_high_path, lora_high_weight, device=device, dtype=weight_dtype, sub_transformer_name="transformer_2")
|
||||
|
||||
if enable_latent_upsample:
|
||||
lu_kwargs = OmegaConf.to_container(config['latent_upsampler_kwargs'], resolve=True)
|
||||
lu_subpath = lu_kwargs.pop('latent_upsampler_subpath', 'latent_upsampler')
|
||||
|
||||
if latent_upsampler_path is None:
|
||||
latent_upsampler_path = os.path.join(model_name, lu_subpath)
|
||||
print(f"From latent_upsampler checkpoint: {latent_upsampler_path}")
|
||||
|
||||
if os.path.isdir(latent_upsampler_path):
|
||||
latent_upsampler = WanLatentUpsamplerModel.from_pretrained(
|
||||
latent_upsampler_path,
|
||||
in_channels=vae.config.latent_channels,
|
||||
**lu_kwargs,
|
||||
)
|
||||
else:
|
||||
latent_upsampler = WanLatentUpsamplerModel(
|
||||
in_channels=vae.config.latent_channels,
|
||||
**lu_kwargs,
|
||||
)
|
||||
if latent_upsampler_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
state_dict = load_file(latent_upsampler_path)
|
||||
else:
|
||||
state_dict = torch.load(latent_upsampler_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = latent_upsampler.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
latent_upsampler.eval().to(device, dtype=weight_dtype)
|
||||
|
||||
upsample_pipeline = WanLatentUpsamplePipeline(
|
||||
vae=pipeline.vae,
|
||||
latent_upsampler=latent_upsampler,
|
||||
)
|
||||
upsample_pipeline.to(device=device, dtype=weight_dtype)
|
||||
|
||||
with torch.no_grad():
|
||||
upsampled = upsample_pipeline(
|
||||
latents=sample,
|
||||
output_type="pt",
|
||||
return_dict=False,
|
||||
)
|
||||
sample = upsampled[0]
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
if video_length == 1:
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
|
||||
image = sample[0, :, 0]
|
||||
image = image.transpose(0, 1).transpose(1, 2)
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
else:
|
||||
save_results()
|
||||
@@ -0,0 +1,421 @@
|
||||
import os
|
||||
import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from diffusers import FlowMatchEulerDiscreteScheduler
|
||||
from omegaconf import OmegaConf
|
||||
from PIL import Image
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
project_roots = [os.path.dirname(current_file_path), os.path.dirname(os.path.dirname(current_file_path)), os.path.dirname(os.path.dirname(os.path.dirname(current_file_path)))]
|
||||
for project_root in project_roots:
|
||||
sys.path.insert(0, project_root) if project_root not in sys.path else None
|
||||
|
||||
from videox_fun.dist import set_multi_gpus_devices, shard_model
|
||||
from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8, AutoencoderTinyWan,
|
||||
AutoTokenizer, Wan2_2Transformer3DModel,
|
||||
WanLatentUpsamplerModel,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.models.cache_utils import get_teacache_coefficients
|
||||
from videox_fun.pipeline import Wan2_2Pipeline, WanLatentUpsamplePipeline
|
||||
from videox_fun.utils import (register_auto_device_hook,
|
||||
safe_enable_group_offload)
|
||||
from videox_fun.utils.fm_solvers import FlowDPMSolverMultistepScheduler
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fp8_optimization import (convert_model_weight_to_float8,
|
||||
convert_weight_dtype_wrapper,
|
||||
replace_parameters_by_name)
|
||||
from videox_fun.utils.lora_utils import merge_lora, unmerge_lora
|
||||
from videox_fun.utils.utils import (filter_kwargs, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
# GPU memory mode, which can be chosen in [model_full_load, model_full_load_and_qfloat8, model_cpu_offload, model_cpu_offload_and_qfloat8, model_group_offload, sequential_cpu_offload].
|
||||
# model_full_load means that the entire model will be moved to the GPU.
|
||||
#
|
||||
# model_full_load_and_qfloat8 means that the entire model will be moved to the GPU,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_cpu_offload means that the entire model will be moved to the CPU after use, which can save some GPU memory.
|
||||
#
|
||||
# model_cpu_offload_and_qfloat8 indicates that the entire model will be moved to the CPU after use,
|
||||
# and the transformer model has been quantized to float8, which can save more GPU memory.
|
||||
#
|
||||
# model_group_offload transfers internal layer groups between CPU/CUDA,
|
||||
# balancing memory efficiency and speed between full-module and leaf-level offloading methods.
|
||||
#
|
||||
# sequential_cpu_offload means that each layer of the model will be moved to the CPU after use,
|
||||
# resulting in slower speeds but saving a large amount of GPU memory.
|
||||
GPU_memory_mode = "sequential_cpu_offload"
|
||||
# Multi GPUs config
|
||||
# Please ensure that the product of ulysses_degree and ring_degree equals the number of GPUs used.
|
||||
# For example, if you are using 8 GPUs, you can set ulysses_degree = 2 and ring_degree = 4.
|
||||
# If you are using 1 GPU, you can set ulysses_degree = 1 and ring_degree = 1.
|
||||
ulysses_degree = 1
|
||||
ring_degree = 1
|
||||
# Use FSDP to save more GPU memory in multi gpus.
|
||||
fsdp_dit = False
|
||||
fsdp_text_encoder = True
|
||||
# Compile will give a speedup in fixed resolution and need a little GPU memory.
|
||||
# The compile_dit is not compatible with the fsdp_dit and sequential_cpu_offload.
|
||||
compile_dit = False
|
||||
|
||||
# TeaCache config
|
||||
enable_teacache = True
|
||||
# Recommended to be set between 0.05 and 0.30. A larger threshold can cache more steps, speeding up the inference process,
|
||||
# but it may cause slight differences between the generated content and the original content.
|
||||
teacache_threshold = 0.10
|
||||
# The number of steps to skip TeaCache at the beginning of the inference process, which can
|
||||
# reduce the impact of TeaCache on generated video quality.
|
||||
num_skip_start_steps = 5
|
||||
# Whether to offload TeaCache tensors to cpu to save a little bit of GPU memory.
|
||||
teacache_offload = False
|
||||
|
||||
# Skip some cfg steps in inference
|
||||
# Recommended to be set between 0.00 and 0.25
|
||||
cfg_skip_ratio = 0
|
||||
|
||||
# Riflex config
|
||||
enable_riflex = False
|
||||
# Index of intrinsic frequency
|
||||
riflex_k = 6
|
||||
|
||||
# Config and model path
|
||||
config_path = "config/wan2.2/wan_civitai_t2v_2.2vae.yaml"
|
||||
# model path
|
||||
model_name = "models/Diffusion_Transformer/Wan2.2-Fun-T2V-A14B-2.2VAE"
|
||||
|
||||
# TAE (Tiny AutoEncoder): shares the Wan2.2 VAE latent space but decodes much
|
||||
# cheaper (<0.5GB vs ~6-9GB), at the cost of fine detail. Weights: taew2_2.safetensors.
|
||||
tae_path = "models/Diffusion_Transformer/taew2_2.safetensors"
|
||||
|
||||
# Choose the sampler in "Flow", "Flow_Unipc", "Flow_DPM++"
|
||||
sampler_name = "Flow"
|
||||
# [NOTE]: Noise schedule shift parameter. Affects temporal dynamics.
|
||||
# Used when the sampler is in "Flow_Unipc", "Flow_DPM++".
|
||||
shift = 5
|
||||
|
||||
# Latent upsampler config
|
||||
# The latent upsampler spatially upsamples the generated latents before VAE decoding.
|
||||
enable_latent_upsample = True
|
||||
|
||||
# Load pretrained model if need
|
||||
# The transformer_path is used for low noise model, the transformer_high_path is used for high noise model.
|
||||
transformer_path = None
|
||||
transformer_high_path = None
|
||||
vae_path = None
|
||||
# Load pretrained latent upsampler model if need.
|
||||
# If latent_upsampler_path is None, the latent_upsampler_subpath subfolder of model_name will be used.
|
||||
latent_upsampler_path = None
|
||||
# Load lora model if need
|
||||
# The lora_path is used for low noise model, the lora_high_path is used for high noise model.
|
||||
lora_path = None
|
||||
lora_high_path = None
|
||||
|
||||
# Other params
|
||||
sample_size = [480, 832]
|
||||
video_length = 81
|
||||
fps = 16
|
||||
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
# 使用更长的neg prompt如"模糊,突变,变形,失真,画面暗,文本字幕,画面固定,连环画,漫画,线稿,没有主体。",可以增加稳定性
|
||||
# 在neg prompt中添加"安静,固定"等词语可以增加动态性。
|
||||
prompt = "一只棕色的狗摇着头,坐在舒适房间里的浅色沙发上。在狗的后面,架子上有一幅镶框的画,周围是粉红色的花朵。房间里柔和温暖的灯光营造出舒适的氛围。"
|
||||
negative_prompt = "色调艳丽,过曝,静态,细节模糊不清,字幕,风格,作品,画作,画面,静止,整体发灰,最差质量,低质量,JPEG压缩残留,丑陋的,残缺的,多余的手指,画得不好的手部,画得不好的脸部,畸形的,毁容的,形态畸形的肢体,手指融合,静止不动的画面,杂乱的背景,三条腿,背景人很多,倒着走"
|
||||
guidance_scale = 6.0
|
||||
seed = 43
|
||||
num_inference_steps = 50
|
||||
# The lora_weight is used for low noise model, the lora_high_weight is used for high noise model.
|
||||
lora_weight = 0.55
|
||||
lora_high_weight = 0.55
|
||||
save_path = "samples/wan-videos-fun-t2v-2.2vae-tae"
|
||||
|
||||
device = set_multi_gpus_devices(ulysses_degree, ring_degree)
|
||||
config = OmegaConf.load(config_path)
|
||||
# Override the VAE with AutoencoderTinyWan (TAE); everything else (latent
|
||||
# channels, patch size, compression ratios) is inferred from the weight file.
|
||||
config['vae_kwargs'] = OmegaConf.create({
|
||||
'vae_type': 'AutoencoderTinyWan',
|
||||
'vae_subpath': tae_path,
|
||||
})
|
||||
boundary = config['transformer_additional_kwargs'].get('boundary', 0.900)
|
||||
|
||||
transformer = Wan2_2Transformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_low_noise_model_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
if config['transformer_additional_kwargs'].get('transformer_combination_type', 'single') == "moe":
|
||||
transformer_2 = Wan2_2Transformer3DModel.from_pretrained(
|
||||
os.path.join(model_name, config['transformer_additional_kwargs'].get('transformer_high_noise_model_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
else:
|
||||
transformer_2 = None
|
||||
|
||||
if transformer_path is not None:
|
||||
print(f"From checkpoint: {transformer_path}")
|
||||
if transformer_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
if transformer_2 is not None:
|
||||
if transformer_high_path is not None:
|
||||
print(f"From checkpoint: {transformer_high_path}")
|
||||
if transformer_high_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(transformer_high_path)
|
||||
else:
|
||||
state_dict = torch.load(transformer_high_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer_2.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Vae
|
||||
Chosen_AutoencoderKL = {
|
||||
"AutoencoderKLWan": AutoencoderKLWan,
|
||||
"AutoencoderKLWan3_8": AutoencoderKLWan3_8,
|
||||
"AutoencoderTinyWan": AutoencoderTinyWan
|
||||
}[config['vae_kwargs'].get('vae_type', 'AutoencoderKLWan')]
|
||||
vae = Chosen_AutoencoderKL.from_pretrained(
|
||||
os.path.join(model_name, config['vae_kwargs'].get('vae_subpath', 'vae')),
|
||||
additional_kwargs=OmegaConf.to_container(config['vae_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
if vae_path is not None:
|
||||
print(f"From checkpoint: {vae_path}")
|
||||
if vae_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file, safe_open
|
||||
state_dict = load_file(vae_path)
|
||||
else:
|
||||
state_dict = torch.load(vae_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
if isinstance(vae, AutoencoderTinyWan):
|
||||
state_dict = vae.model.patch_tgrow_layers(state_dict)
|
||||
m, u = vae.model.load_state_dict(state_dict, strict=False)
|
||||
else:
|
||||
m, u = vae.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
# Get Tokenizer
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('tokenizer_subpath', 'tokenizer')),
|
||||
)
|
||||
|
||||
# Get Text encoder
|
||||
text_encoder = WanT5EncoderModel.from_pretrained(
|
||||
os.path.join(model_name, config['text_encoder_kwargs'].get('text_encoder_subpath', 'text_encoder')),
|
||||
additional_kwargs=OmegaConf.to_container(config['text_encoder_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
)
|
||||
text_encoder = text_encoder.eval()
|
||||
|
||||
# Get Scheduler
|
||||
Chosen_Scheduler = scheduler_dict = {
|
||||
"Flow": FlowMatchEulerDiscreteScheduler,
|
||||
"Flow_Unipc": FlowUniPCMultistepScheduler,
|
||||
"Flow_DPM++": FlowDPMSolverMultistepScheduler,
|
||||
}[sampler_name]
|
||||
if sampler_name == "Flow_Unipc" or sampler_name == "Flow_DPM++":
|
||||
config['scheduler_kwargs']['shift'] = 1
|
||||
scheduler = Chosen_Scheduler(
|
||||
**filter_kwargs(Chosen_Scheduler, OmegaConf.to_container(config['scheduler_kwargs']))
|
||||
)
|
||||
|
||||
# Get Pipeline
|
||||
pipeline = Wan2_2Pipeline(
|
||||
transformer=transformer,
|
||||
transformer_2=transformer_2,
|
||||
vae=vae,
|
||||
tokenizer=tokenizer,
|
||||
text_encoder=text_encoder,
|
||||
scheduler=scheduler,
|
||||
)
|
||||
if ulysses_degree > 1 or ring_degree > 1:
|
||||
from functools import partial
|
||||
transformer.enable_multi_gpus_inference()
|
||||
if transformer_2 is not None:
|
||||
transformer_2.enable_multi_gpus_inference()
|
||||
if fsdp_dit:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.transformer = shard_fn(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2 = shard_fn(pipeline.transformer_2)
|
||||
print("Add FSDP DIT")
|
||||
if fsdp_text_encoder:
|
||||
shard_fn = partial(shard_model, device_id=device, param_dtype=weight_dtype)
|
||||
pipeline.text_encoder = shard_fn(pipeline.text_encoder)
|
||||
print("Add FSDP TEXT ENCODER")
|
||||
|
||||
if compile_dit:
|
||||
for i in range(len(pipeline.transformer.blocks)):
|
||||
pipeline.transformer.blocks[i] = torch.compile(pipeline.transformer.blocks[i])
|
||||
if transformer_2 is not None:
|
||||
for i in range(len(pipeline.transformer_2.blocks)):
|
||||
pipeline.transformer_2.blocks[i] = torch.compile(pipeline.transformer_2.blocks[i])
|
||||
print("Add Compile")
|
||||
|
||||
if GPU_memory_mode == "sequential_cpu_offload":
|
||||
replace_parameters_by_name(transformer, ["modulation",], device=device)
|
||||
transformer.freqs = transformer.freqs.to(device=device)
|
||||
if transformer_2 is not None:
|
||||
replace_parameters_by_name(transformer_2, ["modulation",], device=device)
|
||||
transformer_2.freqs = transformer_2.freqs.to(device=device)
|
||||
pipeline.enable_sequential_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_group_offload":
|
||||
register_auto_device_hook(pipeline.transformer)
|
||||
if transformer_2 is not None:
|
||||
register_auto_device_hook(pipeline.transformer_2)
|
||||
safe_enable_group_offload(pipeline, onload_device=device, offload_device="cpu", offload_type="leaf_level", use_stream=True)
|
||||
elif GPU_memory_mode == "model_cpu_offload_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_cpu_offload":
|
||||
pipeline.enable_model_cpu_offload(device=device)
|
||||
elif GPU_memory_mode == "model_full_load_and_qfloat8":
|
||||
convert_model_weight_to_float8(transformer, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer, weight_dtype)
|
||||
if transformer_2 is not None:
|
||||
convert_model_weight_to_float8(transformer_2, exclude_module_name=["modulation",], device=device)
|
||||
convert_weight_dtype_wrapper(transformer_2, weight_dtype)
|
||||
pipeline.to(device=device)
|
||||
else:
|
||||
pipeline.to(device=device)
|
||||
|
||||
coefficients = get_teacache_coefficients(model_name) if enable_teacache else None
|
||||
if coefficients is not None:
|
||||
print(f"Enable TeaCache with threshold {teacache_threshold} and skip the first {num_skip_start_steps} steps.")
|
||||
pipeline.transformer.enable_teacache(
|
||||
coefficients, num_inference_steps, teacache_threshold, num_skip_start_steps=num_skip_start_steps, offload=teacache_offload
|
||||
)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.share_teacache(transformer=pipeline.transformer)
|
||||
|
||||
if cfg_skip_ratio is not None:
|
||||
print(f"Enable cfg_skip_ratio {cfg_skip_ratio}.")
|
||||
pipeline.transformer.enable_cfg_skip(cfg_skip_ratio, num_inference_steps)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.share_cfg_skip(transformer=pipeline.transformer)
|
||||
|
||||
generator = torch.Generator(device=device).manual_seed(seed)
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = merge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
if lora_high_path is not None and transformer_2 is not None:
|
||||
pipeline = merge_lora(pipeline, lora_high_path, lora_high_weight, device=device, dtype=weight_dtype, sub_transformer_name="transformer_2")
|
||||
|
||||
with torch.no_grad():
|
||||
video_length = int((video_length - 1) // vae.config.temporal_compression_ratio * vae.config.temporal_compression_ratio) + 1 if video_length != 1 else 1
|
||||
latent_frames = (video_length - 1) // vae.config.temporal_compression_ratio + 1
|
||||
|
||||
if enable_riflex:
|
||||
pipeline.transformer.enable_riflex(k = riflex_k, L_test = latent_frames)
|
||||
if transformer_2 is not None:
|
||||
pipeline.transformer_2.enable_riflex(k = riflex_k, L_test = latent_frames)
|
||||
|
||||
sample = pipeline(
|
||||
prompt,
|
||||
num_frames = video_length,
|
||||
negative_prompt = negative_prompt,
|
||||
height = sample_size[0],
|
||||
width = sample_size[1],
|
||||
generator = generator,
|
||||
guidance_scale = guidance_scale,
|
||||
num_inference_steps = num_inference_steps,
|
||||
boundary = boundary,
|
||||
shift = shift,
|
||||
output_type = "latent" if enable_latent_upsample else "pil",
|
||||
).videos
|
||||
|
||||
if lora_path is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_path, lora_weight, device=device, dtype=weight_dtype)
|
||||
if lora_high_path is not None and transformer_2 is not None:
|
||||
pipeline = unmerge_lora(pipeline, lora_high_path, lora_high_weight, device=device, dtype=weight_dtype, sub_transformer_name="transformer_2")
|
||||
|
||||
if enable_latent_upsample:
|
||||
lu_kwargs = OmegaConf.to_container(config['latent_upsampler_kwargs'], resolve=True)
|
||||
lu_subpath = lu_kwargs.pop('latent_upsampler_subpath', 'latent_upsampler')
|
||||
|
||||
if latent_upsampler_path is None:
|
||||
latent_upsampler_path = os.path.join(model_name, lu_subpath)
|
||||
print(f"From latent_upsampler checkpoint: {latent_upsampler_path}")
|
||||
|
||||
if os.path.isdir(latent_upsampler_path):
|
||||
latent_upsampler = WanLatentUpsamplerModel.from_pretrained(
|
||||
latent_upsampler_path,
|
||||
in_channels=vae.config.latent_channels,
|
||||
**lu_kwargs,
|
||||
)
|
||||
else:
|
||||
latent_upsampler = WanLatentUpsamplerModel(
|
||||
in_channels=vae.config.latent_channels,
|
||||
**lu_kwargs,
|
||||
)
|
||||
if latent_upsampler_path.endswith("safetensors"):
|
||||
from safetensors.torch import load_file
|
||||
state_dict = load_file(latent_upsampler_path)
|
||||
else:
|
||||
state_dict = torch.load(latent_upsampler_path, map_location="cpu")
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = latent_upsampler.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
latent_upsampler.eval().to(device, dtype=weight_dtype)
|
||||
|
||||
upsample_pipeline = WanLatentUpsamplePipeline(
|
||||
vae=pipeline.vae,
|
||||
latent_upsampler=latent_upsampler,
|
||||
)
|
||||
upsample_pipeline.to(device=device, dtype=weight_dtype)
|
||||
|
||||
with torch.no_grad():
|
||||
upsampled = upsample_pipeline(
|
||||
latents=sample,
|
||||
output_type="pt",
|
||||
return_dict=False,
|
||||
)
|
||||
sample = upsampled[0]
|
||||
|
||||
def save_results():
|
||||
if not os.path.exists(save_path):
|
||||
os.makedirs(save_path, exist_ok=True)
|
||||
|
||||
index = len([path for path in os.listdir(save_path)]) + 1
|
||||
prefix = str(index).zfill(8)
|
||||
if video_length == 1:
|
||||
video_path = os.path.join(save_path, prefix + ".png")
|
||||
|
||||
image = sample[0, :, 0]
|
||||
image = image.transpose(0, 1).transpose(1, 2)
|
||||
image = (image * 255).numpy().astype(np.uint8)
|
||||
image = Image.fromarray(image)
|
||||
image.save(video_path)
|
||||
else:
|
||||
video_path = os.path.join(save_path, prefix + ".mp4")
|
||||
save_videos_grid(sample, video_path, fps=fps)
|
||||
|
||||
if ulysses_degree * ring_degree > 1:
|
||||
import torch.distributed as dist
|
||||
if dist.get_rank() == 0:
|
||||
save_results()
|
||||
else:
|
||||
save_results()
|
||||
@@ -46,7 +46,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import T5EncoderModel, T5Tokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -73,8 +72,10 @@ from videox_fun.pipeline.pipeline_cogvideox_fun_inpaint import (
|
||||
add_noise_to_reference_video, get_3d_rotary_pos_embed,
|
||||
get_resize_crop_region_for_grid)
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.lora_utils import (create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
@@ -843,7 +844,8 @@ def main():
|
||||
)
|
||||
|
||||
transformer3d = CogVideoXTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer"
|
||||
args.pretrained_model_name_or_path, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -893,10 +895,17 @@ def main():
|
||||
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
ema_transformer3d = CogVideoXTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer"
|
||||
ema_module = CogVideoXTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=CogVideoXTransformer3DModel, model_config=ema_transformer3d.config)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=CogVideoXTransformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -913,8 +922,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -941,6 +955,7 @@ def main():
|
||||
_, ema_kwargs = CogVideoXTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = CogVideoXTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=CogVideoXTransformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -955,7 +970,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = CogVideoXTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1363,7 +1379,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1748,27 +1764,37 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1777,29 +1803,40 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer3d = unwrap_model(transformer3d)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -45,7 +45,6 @@ from packaging import version
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
import datasets
|
||||
@@ -71,6 +70,8 @@ from videox_fun.pipeline.pipeline_cogvideox_fun_inpaint import (
|
||||
add_noise_to_reference_video, get_3d_rotary_pos_embed,
|
||||
get_resize_crop_region_for_grid)
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
@@ -627,6 +628,9 @@ def parse_args():
|
||||
parser.add_argument(
|
||||
"--use_deepspeed", action="store_true", help="Whether or not to use deepspeed."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--use_fsdp", action="store_true", help="Whether or not to use fsdp."
|
||||
)
|
||||
parser.add_argument(
|
||||
"--low_vram", action="store_true", help="Whether enable low_vram mode."
|
||||
)
|
||||
@@ -803,7 +807,8 @@ def main():
|
||||
vae = vae.eval()
|
||||
|
||||
transformer3d = CogVideoXTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer"
|
||||
args.pretrained_model_name_or_path, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -853,10 +858,17 @@ def main():
|
||||
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
ema_transformer3d = CogVideoXTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer"
|
||||
ema_module = CogVideoXTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=CogVideoXTransformer3DModel, model_config=ema_transformer3d.config)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=CogVideoXTransformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -873,8 +885,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -901,6 +918,7 @@ def main():
|
||||
_, ema_kwargs = CogVideoXTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = CogVideoXTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=CogVideoXTransformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -915,7 +933,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = CogVideoXTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1315,7 +1334,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1655,27 +1674,37 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1684,29 +1713,40 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer3d = unwrap_model(transformer3d)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -46,7 +46,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
import datasets
|
||||
@@ -75,6 +74,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
@@ -842,7 +842,8 @@ def main():
|
||||
)
|
||||
|
||||
transformer3d = CogVideoXTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer"
|
||||
args.pretrained_model_name_or_path, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -1410,7 +1411,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1770,37 +1771,47 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1809,17 +1820,23 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -66,6 +66,7 @@ from videox_fun.pipeline.pipeline_cogvideox_fun_inpaint import (
|
||||
CogVideoXFunInpaintPipeline, get_3d_rotary_pos_embed,
|
||||
get_resize_crop_region_for_grid)
|
||||
from videox_fun.utils.lora_utils import create_network, merge_lora
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -98,6 +99,7 @@ def log_validation(vae, text_encoder, tokenizer, transformer3d, network,
|
||||
|
||||
transformer3d_val = CogVideoXTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
transformer3d_val.load_state_dict(accelerator.unwrap_model(transformer3d).state_dict())
|
||||
scheduler = DDIMScheduler.from_pretrained(args.pretrained_model_name_or_path, subfolder="scheduler")
|
||||
@@ -875,7 +877,8 @@ def main():
|
||||
)
|
||||
|
||||
transformer3d = CogVideoXTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer"
|
||||
args.pretrained_model_name_or_path, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -1115,7 +1118,7 @@ def main():
|
||||
accelerator.print(f"\nsaving checkpoint: {ckpt_file}")
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1364,49 +1367,59 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
# Validation (distributed)
|
||||
if do_validation and (global_step % args.validation_steps) == 0:
|
||||
if args.validation_prompts is None and args.validation_prompt_path.endswith(".txt"):
|
||||
validation_prompts = []
|
||||
with open(args.validation_prompt_path, "r") as f:
|
||||
for line in f:
|
||||
validation_prompts.append(line.strip())
|
||||
# Do not select randomly to ensure that `args.validation_prompts` is the same for each process.
|
||||
args.validation_prompts = validation_prompts[:args.validation_batch_size]
|
||||
|
||||
validation_prompts_idx = [(i, p) for i, p in enumerate(args.validation_prompts)]
|
||||
|
||||
if hasattr(vae, "enable_cache_in_vae"):
|
||||
vae.enable_cache_in_vae()
|
||||
accelerator.wait_for_everyone()
|
||||
with accelerator.split_between_processes(validation_prompts_idx) as splitted_prompts_idx:
|
||||
validation_loss, validation_reward = log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
loss_fn,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
splitted_prompts_idx
|
||||
)
|
||||
avg_validation_loss = accelerator.gather(validation_loss).mean()
|
||||
avg_validation_reward = accelerator.gather(validation_reward).mean()
|
||||
if accelerator.is_main_process:
|
||||
accelerator.log({"validation_loss": avg_validation_loss, "validation_reward": avg_validation_reward}, step=global_step)
|
||||
accelerator.wait_for_everyone()
|
||||
with progress_bar.paused():
|
||||
if args.validation_prompts is None and args.validation_prompt_path.endswith(".txt"):
|
||||
validation_prompts = []
|
||||
with open(args.validation_prompt_path, "r") as f:
|
||||
for line in f:
|
||||
validation_prompts.append(line.strip())
|
||||
# Do not select randomly to ensure that `args.validation_prompts` is the same for each process.
|
||||
args.validation_prompts = validation_prompts[:args.validation_batch_size]
|
||||
|
||||
validation_prompts_idx = [(i, p) for i, p in enumerate(args.validation_prompts)]
|
||||
|
||||
if hasattr(vae, "enable_cache_in_vae"):
|
||||
vae.enable_cache_in_vae()
|
||||
accelerator.wait_for_everyone()
|
||||
with accelerator.split_between_processes(validation_prompts_idx) as splitted_prompts_idx:
|
||||
validation_loss, validation_reward = log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
loss_fn,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
splitted_prompts_idx
|
||||
)
|
||||
avg_validation_loss = accelerator.gather(validation_loss).mean()
|
||||
avg_validation_reward = accelerator.gather(validation_reward).mean()
|
||||
if accelerator.is_main_process:
|
||||
accelerator.log({"validation_loss": avg_validation_loss, "validation_reward": avg_validation_reward}, step=global_step)
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "step_reward": reward.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1414,6 +1427,11 @@ def main():
|
||||
if global_step >= args.max_train_steps:
|
||||
break
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
|
||||
@@ -53,7 +53,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -75,6 +74,8 @@ from videox_fun.models import (AutoencoderKLFlux2, AutoTokenizer,
|
||||
Mistral3Model)
|
||||
from videox_fun.pipeline import ErnieImagePipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -793,6 +794,7 @@ def main():
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -843,15 +845,21 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = ErnieImageTransformer2DModel.from_pretrained(
|
||||
ema_module = ErnieImageTransformer2DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=ErnieImageTransformer2DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=ErnieImageTransformer2DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -868,8 +876,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -896,6 +909,7 @@ def main():
|
||||
_, ema_kwargs = ErnieImageTransformer2DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = ErnieImageTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=ErnieImageTransformer2DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -910,7 +924,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = ErnieImageTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1297,7 +1312,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1531,27 +1546,37 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1560,23 +1585,29 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -54,7 +54,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -77,6 +76,8 @@ from videox_fun.models import (AutoencoderKLWan, CLIPModel,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.pipeline import FantasyTalkingPipeline, WanFunPipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions,
|
||||
get_image_to_video_latent,
|
||||
merge_video_audio, save_videos_grid)
|
||||
@@ -884,7 +885,7 @@ def main():
|
||||
else:
|
||||
state_dict = state_dict["state_dict"] if "state_dict" in state_dict else state_dict
|
||||
|
||||
m, u = transformer.load_state_dict(state_dict, strict=False)
|
||||
m, u = transformer3d.load_state_dict(state_dict, strict=False)
|
||||
print(f"missing keys: {len(m)}, unexpected keys: {len(u)}")
|
||||
|
||||
if args.vae_path is not None:
|
||||
@@ -917,14 +918,20 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = FantasyTalkingTransformer3DModel.from_pretrained(
|
||||
ema_module = FantasyTalkingTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=FantasyTalkingTransformer3DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=FantasyTalkingTransformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -941,8 +948,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -969,7 +981,8 @@ def main():
|
||||
_, ema_kwargs = FantasyTalkingTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = FantasyTalkingTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs'])
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=FantasyTalkingTransformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -984,7 +997,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = FantasyTalkingTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1452,7 +1466,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1854,30 +1868,40 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1886,32 +1910,43 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer3d = unwrap_model(transformer3d)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -181,7 +181,7 @@ export DATASET_META_NAME="/mnt/data/metadata_add_width_height.json"
|
||||
mkdir -p models/Diffusion_Transformer
|
||||
|
||||
# Download FlashHead official weights
|
||||
modelscope download --model AI-ModelScope/SoulX-FlashHead-1_3B --local_dir models/Diffusion_Transformer/SoulX-FlashHead-1_3B
|
||||
modelscope download --model Soul-AILab/SoulX-FlashHead-1_3B --local_dir models/Diffusion_Transformer/SoulX-FlashHead-1_3B
|
||||
|
||||
# Download audio encoder (wav2vec2)
|
||||
modelscope download --model AI-ModelScope/wav2vec2-base-960h --local_dir models/Diffusion_Transformer/wav2vec2-base-960h
|
||||
|
||||
@@ -54,7 +54,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -76,6 +75,8 @@ from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
FlashHeadTransformer3DModel)
|
||||
from videox_fun.pipeline import FlashHeadPipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
@@ -874,14 +875,20 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = FlashHeadTransformer3DModel.from_pretrained(
|
||||
ema_module = FlashHeadTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, "Model_Pro", config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=FlashHeadTransformer3DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=FlashHeadTransformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -898,8 +905,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -926,7 +938,8 @@ def main():
|
||||
_, ema_kwargs = FlashHeadTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = FlashHeadTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs'])
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=FlashHeadTransformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -941,7 +954,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = FlashHeadTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1380,7 +1394,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1742,27 +1756,37 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if global_step % args.validation_steps == 0 and args.validation_image_paths is not None:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1771,29 +1795,40 @@ def main():
|
||||
break
|
||||
|
||||
if epoch % args.validation_epochs == 0 and args.validation_image_paths is not None:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer3d = unwrap_model(transformer3d)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -54,7 +54,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import \
|
||||
AutoTokenizer # Not used in FlashHead, but kept for compatibility
|
||||
from transformers.utils import ContextManagers
|
||||
@@ -81,6 +80,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
@@ -1360,7 +1360,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1697,37 +1697,47 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_image_paths is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1736,17 +1746,23 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_image_paths is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
+78
-47
@@ -52,7 +52,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -78,6 +77,8 @@ from videox_fun.models import (AutoencoderKL, AutoencoderKLWan,
|
||||
T5EncoderModel, T5TokenizerFast)
|
||||
from videox_fun.pipeline import FluxPipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -851,6 +852,7 @@ def main():
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -902,15 +904,21 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = FluxTransformer2DModel.from_pretrained(
|
||||
ema_module = FluxTransformer2DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=FluxTransformer2DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=FluxTransformer2DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -927,8 +935,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -955,6 +968,7 @@ def main():
|
||||
_, ema_kwargs = FluxTransformer2DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = FluxTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=FluxTransformer2DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -969,7 +983,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = FluxTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1358,7 +1373,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1607,29 +1622,39 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1638,25 +1663,31 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
+61
-44
@@ -53,7 +53,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -81,6 +80,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -859,6 +859,7 @@ def main():
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -1408,7 +1409,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1632,39 +1633,49 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1673,19 +1684,25 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
+74
-43
@@ -53,7 +53,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -79,6 +78,8 @@ from videox_fun.models import (AutoencoderKLFlux2, CLIPImageProcessor,
|
||||
Qwen2Tokenizer, QwenImageTransformer2DModel)
|
||||
from videox_fun.pipeline import Flux2Pipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -952,6 +953,7 @@ def main():
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -1002,15 +1004,21 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = Flux2Transformer2DModel.from_pretrained(
|
||||
ema_module = Flux2Transformer2DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=Flux2Transformer2DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=Flux2Transformer2DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -1027,8 +1035,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -1055,6 +1068,7 @@ def main():
|
||||
_, ema_kwargs = Flux2Transformer2DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = Flux2Transformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=Flux2Transformer2DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -1069,7 +1083,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = Flux2Transformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1454,7 +1469,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1695,27 +1710,37 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1724,23 +1749,29 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
+57
-40
@@ -53,7 +53,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -82,6 +81,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -929,6 +929,7 @@ def main():
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -1416,7 +1417,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1632,37 +1633,47 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1671,17 +1682,23 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -52,7 +52,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -77,6 +76,8 @@ from videox_fun.models import (AutoencoderKLFlux2, AutoProcessor,
|
||||
PixtralProcessor)
|
||||
from videox_fun.pipeline import Flux2ControlPipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
@@ -1020,15 +1021,21 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = Flux2ControlTransformer2DModel.from_pretrained(
|
||||
ema_module = Flux2ControlTransformer2DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=Flux2ControlTransformer2DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=Flux2ControlTransformer2DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -1045,8 +1052,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -1073,6 +1085,7 @@ def main():
|
||||
_, ema_kwargs = Flux2ControlTransformer2DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = Flux2ControlTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=Flux2ControlTransformer2DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -1087,7 +1100,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = Flux2ControlTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1496,7 +1510,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1792,34 +1806,44 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
|
||||
for name, param in transformer3d.named_parameters():
|
||||
for trainable_module_name in args.trainable_modules + args.trainable_modules_low_learning_rate:
|
||||
if trainable_module_name not in name:
|
||||
param.requires_grad = False
|
||||
break
|
||||
accelerator.save_state(save_path)
|
||||
transformer3d.requires_grad_(True)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1828,23 +1852,29 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -58,7 +58,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import Dataset, RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -83,6 +82,7 @@ from videox_fun.models import (AutoencoderKLFlux2, AutoProcessor,
|
||||
PixtralProcessor)
|
||||
from videox_fun.pipeline import Flux2ControlPipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
@@ -1078,7 +1078,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = Flux2ControlTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1497,7 +1498,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1803,28 +1804,38 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
|
||||
for name, param in generator_transformer3d.named_parameters():
|
||||
for trainable_module_name in args.trainable_modules + args.trainable_modules_low_learning_rate:
|
||||
if trainable_module_name not in name:
|
||||
param.requires_grad = False
|
||||
break
|
||||
accelerator.save_state(save_path)
|
||||
|
||||
generator_transformer3d.requires_grad_(True)
|
||||
generator_transformer3d.requires_grad_(True)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"avg_cfg_loss": avg_cfg_loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1833,16 +1844,22 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -53,7 +53,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -76,6 +75,8 @@ from videox_fun.models import (AutoencoderKLHunyuanVideo, CLIPImageProcessor,
|
||||
LlavaForConditionalGeneration)
|
||||
from videox_fun.pipeline import HunyuanVideoPipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -974,6 +975,7 @@ def main():
|
||||
# Get Transformer
|
||||
transformer3d = HunyuanVideoTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, 'transformer'),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -1025,13 +1027,19 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = HunyuanVideoTransformer3DModel.from_pretrained(
|
||||
ema_module = HunyuanVideoTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, 'transformer'),
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=HunyuanVideoTransformer3DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=HunyuanVideoTransformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -1048,8 +1056,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -1076,6 +1089,7 @@ def main():
|
||||
_, ema_kwargs = HunyuanVideoTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = HunyuanVideoTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=HunyuanVideoTransformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -1090,7 +1104,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = HunyuanVideoTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1527,7 +1542,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -2041,29 +2056,39 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -2072,31 +2097,42 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer3d = unwrap_model(transformer3d)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -53,7 +53,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -79,6 +78,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (get_image, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
@@ -982,6 +982,7 @@ def main():
|
||||
# Get Transformer
|
||||
transformer3d = HunyuanVideoTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, 'transformer'),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -1512,7 +1513,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -2000,39 +2001,49 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -2041,19 +2052,25 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
text_encoder_2,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -185,10 +185,10 @@ mkdir -p models/Personalized_Model
|
||||
modelscope download --model Wan-AI/Wan2.1-I2V-14B-480P --local_dir models/Diffusion_Transformer/Wan2.1-I2V-14B-480P
|
||||
|
||||
# Download audio encoder (chinese-wav2vec2)
|
||||
modelscope download --model AI-ModelScope/chinese-wav2vec2-base --local_dir models/Diffusion_Transformer/chinese-wav2vec2-base
|
||||
modelscope download --model TencentGameMate/chinese-wav2vec2-base --local_dir models/Diffusion_Transformer/chinese-wav2vec2-base
|
||||
|
||||
# Download InfiniteTalk pretrained weights
|
||||
modelscope download --model amap_cvlab/InfiniteTalk --local_dir models/Personalized_Model/InfiniteTalk/
|
||||
modelscope download --model MeiGen-AI/InfiniteTalk --local_dir models/Personalized_Model/InfiniteTalk/
|
||||
```
|
||||
|
||||
### 3.2 Quick Start (DeepSpeed-Zero-2)
|
||||
|
||||
@@ -180,10 +180,10 @@ mkdir -p models/Personalized_Model
|
||||
modelscope download --model Wan-AI/Wan2.1-I2V-14B-480P --local_dir models/Diffusion_Transformer/Wan2.1-I2V-14B-480P
|
||||
|
||||
# 下载音频编码器(chinese-wav2vec2)
|
||||
modelscope download --model AI-ModelScope/chinese-wav2vec2-base --local_dir models/Diffusion_Transformer/chinese-wav2vec2-base
|
||||
modelscope download --model TencentGameMate/chinese-wav2vec2-base --local_dir models/Diffusion_Transformer/chinese-wav2vec2-base
|
||||
|
||||
# 下载 InfiniteTalk 预训练权重
|
||||
modelscope download --model amap_cvlab/InfiniteTalk --local_dir models/Personalized_Model/InfiniteTalk/
|
||||
modelscope download --model MeiGen-AI/InfiniteTalk --local_dir models/Personalized_Model/InfiniteTalk/
|
||||
```
|
||||
|
||||
### 3.2 快速开始(DeepSpeed-Zero-2)
|
||||
|
||||
@@ -54,7 +54,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -77,6 +76,8 @@ from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
WanT5EncoderModel)
|
||||
from videox_fun.pipeline import InfiniteTalkPipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
@@ -932,14 +933,21 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = InfiniteTalkTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
# Load the EMA copy from the same subpath as the live model.
|
||||
ema_module = InfiniteTalkTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, sub_path),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=InfiniteTalkTransformer3DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=InfiniteTalkTransformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -956,8 +964,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -984,7 +997,8 @@ def main():
|
||||
_, ema_kwargs = InfiniteTalkTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = InfiniteTalkTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs'])
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=InfiniteTalkTransformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -999,7 +1013,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = InfiniteTalkTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1470,7 +1485,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1929,30 +1944,40 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
clip_image_encoder,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
clip_image_encoder,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1961,32 +1986,43 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
clip_image_encoder,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
clip_image_encoder,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer3d = unwrap_model(transformer3d)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -54,7 +54,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -81,6 +80,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
get_video_to_video_latent,
|
||||
@@ -1466,7 +1466,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1904,40 +1904,50 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
clip_image_encoder,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
clip_image_encoder,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1946,20 +1956,26 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
clip_image_encoder,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
clip_image_encoder,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
+74
-43
@@ -53,7 +53,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -75,6 +74,8 @@ from videox_fun.models import (AutoencoderKLFlux2, AutoTokenizer,
|
||||
from videox_fun.pipeline import LensPipeline
|
||||
from videox_fun.pipeline.pipeline_lens import compute_empirical_mu
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -814,6 +815,7 @@ def main():
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Configure Lens text encoder to expose the selected layers consumed by
|
||||
@@ -868,15 +870,21 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = LensTransformer2DModel.from_pretrained(
|
||||
ema_module = LensTransformer2DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=LensTransformer2DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=LensTransformer2DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -893,8 +901,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -921,6 +934,7 @@ def main():
|
||||
_, ema_kwargs = LensTransformer2DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = LensTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=LensTransformer2DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -935,7 +949,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = LensTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1307,7 +1322,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1552,27 +1567,37 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1581,23 +1606,29 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
+57
-40
@@ -52,7 +52,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -75,6 +74,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -816,6 +816,7 @@ def main():
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Configure Lens text encoder to expose the selected layers consumed by
|
||||
@@ -1351,7 +1352,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1562,37 +1563,47 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1601,17 +1612,23 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -61,7 +61,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler as TorchRandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoProcessor
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -85,6 +84,8 @@ from videox_fun.pipeline.pipeline_lingbot_video_i2v import (SPATIAL_MERGE_SIZE,
|
||||
smart_resize)
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fm_solvers_unipc import FlowUniPCMultistepScheduler
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import calculate_dimensions, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -775,15 +776,20 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if fsdp_stage == 3:
|
||||
raise NotImplementedError("FSDP FULL_SHARD does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = LingBotVideoTransformer3DModel.from_pretrained(
|
||||
ema_module = LingBotVideoTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, "transformer"),
|
||||
low_cpu_mem_usage=True,
|
||||
torch_dtype=weight_dtype,
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=LingBotVideoTransformer3DModel, model_config=ema_transformer3d.config)
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=LingBotVideoTransformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -799,8 +805,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -826,6 +837,7 @@ def main():
|
||||
_, ema_kwargs = LingBotVideoTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = LingBotVideoTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=LingBotVideoTransformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -840,7 +852,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = LingBotVideoTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1239,7 +1252,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1449,27 +1462,37 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the transformer parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
processor,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the transformer parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
processor,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1478,29 +1501,40 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the transformer parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
processor,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the transformer parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
processor,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer3d = unwrap_model(transformer3d)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
|
||||
if args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -188,7 +188,7 @@ Fine-tune from a released LingBot-World checkpoint (recommended, matches inferen
|
||||
mkdir -p models/Diffusion_Transformer
|
||||
|
||||
# Camera-pose LingBot-World base weights (same layout as Wan2.2-I2V-A14B).
|
||||
modelscope download --model your-org/lingbot-world-base-cam --local_dir models/Diffusion_Transformer/lingbot-world-base-cam
|
||||
modelscope download --model Robbyant/lingbot-world-base-cam --local_dir models/Diffusion_Transformer/lingbot-world-base-cam
|
||||
```
|
||||
|
||||
You can also start from a plain Wan2.2-I2V-A14B checkpoint. In that case the LingBot-specific layers (`cam_injector_*`, `cam_scale_layer`, `cam_shift_layer`, `patch_embedding_wancamctrl`, `c2ws_hidden_states_layer{1,2}`) are randomly initialized and **must** be included in `--trainable_modules` (see [3.4](#34-trainable-modules)).
|
||||
|
||||
@@ -188,7 +188,7 @@ export DATASET_META_NAME="/mnt/data/lingbot_world/metadata.json"
|
||||
mkdir -p models/Diffusion_Transformer
|
||||
|
||||
# LingBot-World 相机可控基础权重(目录结构与 Wan2.2-I2V-A14B 一致)
|
||||
modelscope download --model your-org/lingbot-world-base-cam --local_dir models/Diffusion_Transformer/lingbot-world-base-cam
|
||||
modelscope download --model Robbyant/lingbot-world-base-cam --local_dir models/Diffusion_Transformer/lingbot-world-base-cam
|
||||
```
|
||||
|
||||
也可以从原始 Wan2.2-I2V-A14B 出发。此时 LingBot 特有的层(`cam_injector_*`、`cam_scale_layer`、`cam_shift_layer`、`patch_embedding_wancamctrl`、`c2ws_hidden_states_layer{1,2}`)会随机初始化,**必须**加入 `--trainable_modules`(详见 [3.4](#34-可训练模块选择))。
|
||||
|
||||
@@ -53,7 +53,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -76,6 +75,8 @@ from videox_fun.models import (AutoencoderKLWan, AutoencoderKLWan3_8,
|
||||
WanTransformer3DModel_LingbotWorld)
|
||||
from videox_fun.pipeline import Wan2_2I2VPipeline, Wan2_2Pipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
@@ -189,12 +190,14 @@ def log_validation(vae, text_encoder, tokenizer, transformer3d, args, config, ac
|
||||
transformer3d_2 = _CompanionCls.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, sub_path),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
else:
|
||||
sub_path = config['transformer_additional_kwargs'].get('transformer_low_noise_model_subpath', 'transformer')
|
||||
transformer3d_1 = _CompanionCls.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, sub_path),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
transformer3d_2 = accelerator.unwrap_model(transformer3d) if type(transformer3d).__name__ == 'DistributedDataParallel' else transformer3d
|
||||
@@ -974,6 +977,7 @@ def main():
|
||||
transformer3d = TransformerCls.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, sub_path),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -1024,14 +1028,21 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = TransformerCls.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
# Load the EMA copy from the same subpath as the live model.
|
||||
ema_module = TransformerCls.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, sub_path),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=TransformerCls, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=TransformerCls, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -1048,8 +1059,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -1076,7 +1092,8 @@ def main():
|
||||
_, ema_kwargs = TransformerCls.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = TransformerCls.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs'])
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=TransformerCls, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -1091,7 +1108,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = TransformerCls.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1549,7 +1567,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1988,28 +2006,38 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -2018,30 +2046,41 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer3d = unwrap_model(transformer3d)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -52,7 +52,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -74,6 +73,8 @@ from videox_fun.models import (AutoencoderKLLongCatVideo, AutoencoderKLWan,
|
||||
from videox_fun.pipeline import (LongCatVideoPipeline, WanI2VPipeline,
|
||||
WanPipeline)
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -851,6 +852,7 @@ def main():
|
||||
# Get Transformer
|
||||
transformer3d = LongCatVideoTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, 'dit'),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -901,13 +903,19 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = LongCatVideoTransformer3DModel.from_pretrained(
|
||||
ema_module = LongCatVideoTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, 'dit'),
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=LongCatVideoTransformer3DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=LongCatVideoTransformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -924,8 +932,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -952,6 +965,7 @@ def main():
|
||||
_, ema_kwargs = LongCatVideoTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = LongCatVideoTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=LongCatVideoTransformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -966,7 +980,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = LongCatVideoTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1401,7 +1416,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1762,27 +1777,37 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1791,29 +1816,40 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer3d = unwrap_model(transformer3d)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -58,7 +58,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -81,6 +80,8 @@ from videox_fun.models import (AutoencoderKLLongCatVideo, AutoTokenizer,
|
||||
UMT5EncoderModel)
|
||||
from videox_fun.pipeline import LongCatVideoAvatarPipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions,
|
||||
get_image_to_video_latent,
|
||||
merge_video_audio, save_videos_grid)
|
||||
@@ -893,6 +894,7 @@ def main():
|
||||
# Get Transformer
|
||||
transformer3d = LongCatVideoAvatarTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_avatar_model_name_or_path, 'avatar_single'),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -943,13 +945,19 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = LongCatVideoAvatarTransformer3DModel.from_pretrained(
|
||||
ema_module = LongCatVideoAvatarTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_avatar_model_name_or_path, 'avatar_single'),
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=LongCatVideoAvatarTransformer3DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=LongCatVideoAvatarTransformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -966,8 +974,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -994,6 +1007,7 @@ def main():
|
||||
_, ema_kwargs = LongCatVideoAvatarTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = LongCatVideoAvatarTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=LongCatVideoAvatarTransformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -1008,7 +1022,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = LongCatVideoAvatarTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1478,7 +1493,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1863,28 +1878,38 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1893,30 +1918,41 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer3d = unwrap_model(transformer3d)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -59,7 +59,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -84,6 +83,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions,
|
||||
get_image_to_video_latent,
|
||||
merge_video_audio, save_videos_grid)
|
||||
@@ -887,6 +887,7 @@ def main():
|
||||
# Get Transformer
|
||||
transformer3d = LongCatVideoAvatarTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_avatar_model_name_or_path, 'avatar_single'),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -1516,7 +1517,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1876,38 +1877,48 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1916,18 +1927,24 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
audio_encoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -50,7 +50,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -73,6 +72,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -841,6 +841,7 @@ def main():
|
||||
# Get Transformer
|
||||
transformer3d = LongCatVideoTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, 'dit'),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -1433,7 +1434,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1769,37 +1770,47 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1808,17 +1819,23 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
+88
-53
@@ -49,7 +49,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
import datasets
|
||||
@@ -71,6 +70,8 @@ from videox_fun.models import (AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video,
|
||||
LTX2VocoderWithBWE)
|
||||
from videox_fun.pipeline import LTX2Pipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid,
|
||||
@@ -987,13 +988,19 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = LTX2VideoTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer"
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=LTX2VideoTransformer3DModel, model_config=ema_transformer3d.config)
|
||||
ema_module = LTX2VideoTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=LTX2VideoTransformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -1010,8 +1017,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -1038,6 +1050,7 @@ def main():
|
||||
_, ema_kwargs = LTX2VideoTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = LTX2VideoTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=LTX2VideoTransformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -1052,7 +1065,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = LTX2VideoTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1573,7 +1587,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -2063,31 +2077,41 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -2096,33 +2120,44 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer3d = unwrap_model(transformer3d)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -48,7 +48,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
import datasets
|
||||
@@ -72,6 +71,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid,
|
||||
@@ -1623,7 +1623,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -2086,41 +2086,51 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -2129,21 +2139,27 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
+86
-51
@@ -49,7 +49,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
import datasets
|
||||
@@ -71,6 +70,8 @@ from videox_fun.models import (AutoencoderKLLTX2Audio, AutoencoderKLLTX2Video,
|
||||
LTX2VideoTransformer3DModel, LTX2Vocoder)
|
||||
from videox_fun.pipeline import LTX2Pipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid,
|
||||
@@ -928,13 +929,19 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = LTX2VideoTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer"
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=LTX2VideoTransformer3DModel, model_config=ema_transformer3d.config)
|
||||
ema_module = LTX2VideoTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=LTX2VideoTransformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -951,8 +958,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -979,6 +991,7 @@ def main():
|
||||
_, ema_kwargs = LTX2VideoTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = LTX2VideoTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=LTX2VideoTransformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -993,7 +1006,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = LTX2VideoTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1505,7 +1519,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1996,30 +2010,40 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -2028,32 +2052,43 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer3d = unwrap_model(transformer3d)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
+62
-46
@@ -48,7 +48,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
import datasets
|
||||
@@ -72,6 +71,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid,
|
||||
@@ -1555,7 +1555,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -2020,40 +2020,50 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -2062,20 +2072,26 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
connectors,
|
||||
vocoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -47,7 +47,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
import datasets
|
||||
@@ -64,6 +63,8 @@ from videox_fun.data import (ASPECT_RATIO_512, ASPECT_RATIO_RANDOM_CROP_512,
|
||||
RandomSampler, VideoDataset,
|
||||
get_closest_ratio, get_random_mask)
|
||||
from videox_fun.models import AutoencoderKLLTX2Video, LTX2LatentUpsamplerModel
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import save_videos_grid
|
||||
|
||||
# Will error if the minimal version of diffusers is not installed.
|
||||
@@ -681,11 +682,17 @@ def main():
|
||||
if args.use_ema:
|
||||
from diffusers.training_utils import EMAModel
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("DeepSpeed ZeRO-3 does not support EMA.")
|
||||
ema_upsampler = LTX2LatentUpsamplerModel.from_pretrained(
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
ema_module = LTX2LatentUpsamplerModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="latent_upsampler"
|
||||
).to(weight_dtype)
|
||||
ema_upsampler = EMAModel(ema_upsampler.parameters(), model_cls=LTX2LatentUpsamplerModel, model_config=ema_upsampler.config)
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_upsampler = FSDPEMA(ema_module, source=latent_upsampler, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_upsampler = EMAModel(ema_module.parameters(), model_cls=LTX2LatentUpsamplerModel, model_config=ema_module.config)
|
||||
|
||||
# ==================== Save/Load Hooks ====================
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -699,8 +706,13 @@ def main():
|
||||
save_file(accelerate_state_dict, safetensor_save_path, metadata={"format": "pt"})
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_upsampler.save_pretrained(os.path.join(output_dir, "latent_upsampler_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_upsampler.load_pretrained(os.path.join(input_dir, "latent_upsampler_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -994,7 +1006,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps), initial=initial_global_step, desc="Steps",
|
||||
disable=not accelerator.is_local_main_process,
|
||||
)
|
||||
@@ -1112,17 +1124,26 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
# Validation
|
||||
if args.validation_paths is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
ema_upsampler.store(latent_upsampler.parameters())
|
||||
ema_upsampler.copy_to(latent_upsampler.parameters())
|
||||
log_validation(vae, latent_upsampler, args, accelerator, weight_dtype, global_step)
|
||||
if args.use_ema:
|
||||
ema_upsampler.restore(latent_upsampler.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
ema_upsampler.store(latent_upsampler.parameters())
|
||||
ema_upsampler.copy_to(latent_upsampler.parameters())
|
||||
log_validation(vae, latent_upsampler, args, accelerator, weight_dtype, global_step)
|
||||
if args.use_ema:
|
||||
ema_upsampler.restore(latent_upsampler.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1132,18 +1153,29 @@ def main():
|
||||
|
||||
# Epoch-level validation
|
||||
if args.validation_paths is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
ema_upsampler.store(latent_upsampler.parameters())
|
||||
ema_upsampler.copy_to(latent_upsampler.parameters())
|
||||
log_validation(vae, latent_upsampler, args, accelerator, weight_dtype, global_step)
|
||||
if args.use_ema:
|
||||
ema_upsampler.restore(latent_upsampler.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
ema_upsampler.store(latent_upsampler.parameters())
|
||||
ema_upsampler.copy_to(latent_upsampler.parameters())
|
||||
log_validation(vae, latent_upsampler, args, accelerator, weight_dtype, global_step)
|
||||
if args.use_ema:
|
||||
ema_upsampler.restore(latent_upsampler.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Final save
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_upsampler.copy_to(latent_upsampler.parameters())
|
||||
if accelerator.is_main_process:
|
||||
latent_upsampler_unwrapped = unwrap_model(latent_upsampler)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_upsampler.copy_to(latent_upsampler_unwrapped.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -181,7 +181,7 @@ export DATASET_META_NAME="/mnt/data/metadata_add_width_height.json"
|
||||
mkdir -p models/Diffusion_Transformer
|
||||
|
||||
# Download MiniMax-H3 official weights
|
||||
hf download MiniMax-AI/MiniMax-H3 --local-dir models/Diffusion_Transformer/MiniMax-H3
|
||||
hf download MiniMaxAI/MiniMax-H3 --local-dir models/Diffusion_Transformer/MiniMax-H3
|
||||
```
|
||||
|
||||
> 💡 The loader accepts either the converted diffusers layout above or an *original* MiniMax-H3 partition (e.g. `MiniMax-H3/FL2VA`); the original shards are converted on the fly while loading, with no intermediate copy on disk.
|
||||
@@ -233,7 +233,7 @@ accelerate launch --mixed_precision="bf16" --use_fsdp --fsdp_auto_wrap_policy TR
|
||||
--low_vram \
|
||||
--trainable_modules "." \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
### 3.3 Common Training Parameters
|
||||
@@ -272,8 +272,8 @@ accelerate launch --mixed_precision="bf16" --use_fsdp --fsdp_auto_wrap_policy TR
|
||||
| `--enable_bucket` | Enable bucket training: trains entire videos grouped by resolution without center cropping | - |
|
||||
| `--uniform_sampling` | Uniform timestep sampling | - |
|
||||
| `--low_vram` | Keep VAE and conditioner on CPU, move to GPU only while encoding | - |
|
||||
| `--train_mode` | `t2v` (text only) or `fl2v` (first-frame keyframe conditioning, the keyframe taken from the training sample itself) | `fl2v` |
|
||||
| `--t2v_ratio` | Under `--train_mode=fl2v`, the fraction of steps that drop the keyframe and train t2v instead, so one run keeps both conditionings. Must be in [0, 1] and only applies to fl2v; 0 trains fl2v only | 0.25 |
|
||||
| `--train_mode` | `t2v` (text only) or `fl2va` (first-frame keyframe conditioning, the keyframe taken from the training sample itself) | `fl2va` |
|
||||
| `--t2v_ratio` | Under `--train_mode=fl2va`, the fraction of steps that drop the keyframe and train t2v instead, so one run keeps both conditionings. Must be in [0, 1] and only applies to fl2va; 0 trains fl2va only | 0.25 |
|
||||
| `--resume_from_checkpoint` | Resume training from checkpoint path, use `"latest"` to auto-select latest | None |
|
||||
| `--trainable_modules` | Trainable modules (`"."` means all modules) | `"."` |
|
||||
| `--validation_steps` | Execute validation every N steps | 2000 |
|
||||
@@ -350,7 +350,7 @@ accelerate launch --use_deepspeed --deepspeed_config_file config/zero_stage2_con
|
||||
--low_vram \
|
||||
--trainable_modules "." \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
### 3.6 Training Without DeepSpeed or FSDP
|
||||
@@ -398,7 +398,7 @@ accelerate launch --mixed_precision="bf16" scripts/minimax_h3/train.py \
|
||||
--low_vram \
|
||||
--trainable_modules "." \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
### 3.7 Multi-Machine Distributed Training
|
||||
@@ -456,7 +456,7 @@ accelerate launch --mixed_precision="bf16" --main_process_ip=$MASTER_ADDR --main
|
||||
--low_vram \
|
||||
--trainable_modules "." \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
**Machine 1 (Worker)**:
|
||||
|
||||
@@ -181,7 +181,7 @@ export DATASET_META_NAME="/mnt/data/metadata_add_width_height.json"
|
||||
mkdir -p models/Diffusion_Transformer
|
||||
|
||||
# Download MiniMax-H3 official weights
|
||||
hf download MiniMax-AI/MiniMax-H3 --local-dir models/Diffusion_Transformer/MiniMax-H3
|
||||
hf download MiniMaxAI/MiniMax-H3 --local-dir models/Diffusion_Transformer/MiniMax-H3
|
||||
```
|
||||
|
||||
> 💡 The loader accepts either the converted diffusers layout above or an *original* MiniMax-H3 partition (e.g. `MiniMax-H3/FL2VA`); the original shards are converted on the fly while loading, with no intermediate copy on disk.
|
||||
@@ -233,7 +233,7 @@ accelerate launch --mixed_precision="bf16" --use_fsdp --fsdp_auto_wrap_policy TR
|
||||
--low_vram \
|
||||
--target_name="to_q,to_k,to_v,ff.0,ff.2,proj_in,audio_proj_in,context_embedder" \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
### 3.3 LoRA Training Parameters
|
||||
@@ -280,8 +280,8 @@ accelerate launch --mixed_precision="bf16" --use_fsdp --fsdp_auto_wrap_policy TR
|
||||
| `--enable_bucket` | Enable bucket training: trains entire videos grouped by resolution without center cropping | - |
|
||||
| `--uniform_sampling` | Uniform timestep sampling | - |
|
||||
| `--low_vram` | Keep VAE and conditioner on CPU, move to GPU only while encoding | - |
|
||||
| `--train_mode` | `t2v` (text only) or `fl2v` (first-frame keyframe conditioning, the keyframe taken from the training sample itself) | `fl2v` |
|
||||
| `--t2v_ratio` | Under `--train_mode=fl2v`, the fraction of steps that drop the keyframe and train t2v instead, so one run keeps both conditionings. Must be in [0, 1] and only applies to fl2v; 0 trains fl2v only | 0.25 |
|
||||
| `--train_mode` | `t2v` (text only) or `fl2va` (first-frame keyframe conditioning, the keyframe taken from the training sample itself) | `fl2va` |
|
||||
| `--t2v_ratio` | Under `--train_mode=fl2va`, the fraction of steps that drop the keyframe and train t2v instead, so one run keeps both conditionings. Must be in [0, 1] and only applies to fl2va; 0 trains fl2va only | 0.25 |
|
||||
| `--resume_from_checkpoint` | Resume training from checkpoint path, use `"latest"` to auto-select latest | None |
|
||||
| `--validation_steps` | Execute validation every N steps | 2000 |
|
||||
| `--validation_epochs` | Execute validation every N epochs | 5 |
|
||||
@@ -357,7 +357,7 @@ accelerate launch --use_deepspeed --deepspeed_config_file config/zero_stage2_con
|
||||
--low_vram \
|
||||
--target_name="to_q,to_k,to_v,ff.0,ff.2,proj_in,audio_proj_in,context_embedder" \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
### 3.6 Training Without DeepSpeed or FSDP
|
||||
@@ -405,7 +405,7 @@ accelerate launch --mixed_precision="bf16" scripts/minimax_h3/train_lora.py \
|
||||
--low_vram \
|
||||
--target_name="to_q,to_k,to_v,ff.0,ff.2,proj_in,audio_proj_in,context_embedder" \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
### 3.7 Multi-Machine Distributed Training
|
||||
@@ -463,7 +463,7 @@ accelerate launch --mixed_precision="bf16" --main_process_ip=$MASTER_ADDR --main
|
||||
--low_vram \
|
||||
--target_name="to_q,to_k,to_v,ff.0,ff.2,proj_in,audio_proj_in,context_embedder" \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
**Machine 1 (Worker)**:
|
||||
|
||||
@@ -181,7 +181,7 @@ export DATASET_META_NAME="/mnt/data/metadata_add_width_height.json"
|
||||
mkdir -p models/Diffusion_Transformer
|
||||
|
||||
# 下载 MiniMax-H3 官方权重
|
||||
hf download MiniMax-AI/MiniMax-H3 --local-dir models/Diffusion_Transformer/MiniMax-H3
|
||||
hf download MiniMaxAI/MiniMax-H3 --local-dir models/Diffusion_Transformer/MiniMax-H3
|
||||
```
|
||||
|
||||
> 💡 加载器既支持上述转换后的 diffusers 布局,也支持*原始的* MiniMax-H3 分片布局(如 `MiniMax-H3/FL2VA`);原始分片会在加载时在线转换,不会在磁盘上产生中间副本。
|
||||
@@ -233,7 +233,7 @@ accelerate launch --mixed_precision="bf16" --use_fsdp --fsdp_auto_wrap_policy TR
|
||||
--low_vram \
|
||||
--target_name="to_q,to_k,to_v,ff.0,ff.2,proj_in,audio_proj_in,context_embedder" \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
### 3.3 LoRA 训练参数
|
||||
@@ -280,8 +280,8 @@ accelerate launch --mixed_precision="bf16" --use_fsdp --fsdp_auto_wrap_policy TR
|
||||
| `--enable_bucket` | 开启 bucket 训练:按分辨率分组训练完整视频,不做中心裁剪 | - |
|
||||
| `--uniform_sampling` | 均匀时间步采样 | - |
|
||||
| `--low_vram` | VAE 与条件器常驻 CPU,仅在编码时移上 GPU | - |
|
||||
| `--train_mode` | `t2v`(纯文本)或 `fl2v`(首帧 keyframe 条件,keyframe 取自训练样本自身) | `fl2v` |
|
||||
| `--t2v_ratio` | 在 `--train_mode=fl2v` 下,按该比例的步数丢弃 keyframe 改训 t2v,使一次训练同时保留两种条件。取值须在 [0, 1] 内且仅适用于 fl2v;0 表示纯 fl2v | 0.25 |
|
||||
| `--train_mode` | `t2v`(纯文本)或 `fl2va`(首帧 keyframe 条件,keyframe 取自训练样本自身) | `fl2va` |
|
||||
| `--t2v_ratio` | 在 `--train_mode=fl2va` 下,按该比例的步数丢弃 keyframe 改训 t2v,使一次训练同时保留两种条件。取值须在 [0, 1] 内且仅适用于 fl2va;0 表示纯 fl2va | 0.25 |
|
||||
| `--resume_from_checkpoint` | 从 checkpoint 路径恢复训练,使用 `"latest"` 自动选择最新 | 无 |
|
||||
| `--validation_steps` | 每 N 步执行一次验证 | 2000 |
|
||||
| `--validation_epochs` | 每 N 个 epoch 执行一次验证 | 5 |
|
||||
@@ -357,7 +357,7 @@ accelerate launch --use_deepspeed --deepspeed_config_file config/zero_stage2_con
|
||||
--low_vram \
|
||||
--target_name="to_q,to_k,to_v,ff.0,ff.2,proj_in,audio_proj_in,context_embedder" \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
### 3.6 不使用 DeepSpeed 或 FSDP 训练
|
||||
@@ -405,7 +405,7 @@ accelerate launch --mixed_precision="bf16" scripts/minimax_h3/train_lora.py \
|
||||
--low_vram \
|
||||
--target_name="to_q,to_k,to_v,ff.0,ff.2,proj_in,audio_proj_in,context_embedder" \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
### 3.7 多机分布式训练
|
||||
@@ -463,7 +463,7 @@ accelerate launch --mixed_precision="bf16" --main_process_ip=$MASTER_ADDR --main
|
||||
--low_vram \
|
||||
--target_name="to_q,to_k,to_v,ff.0,ff.2,proj_in,audio_proj_in,context_embedder" \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
**机器 1(Worker)**:
|
||||
|
||||
@@ -181,7 +181,7 @@ export DATASET_META_NAME="/mnt/data/metadata_add_width_height.json"
|
||||
mkdir -p models/Diffusion_Transformer
|
||||
|
||||
# 下载 MiniMax-H3 官方权重
|
||||
hf download MiniMax-AI/MiniMax-H3 --local-dir models/Diffusion_Transformer/MiniMax-H3
|
||||
hf download MiniMaxAI/MiniMax-H3 --local-dir models/Diffusion_Transformer/MiniMax-H3
|
||||
```
|
||||
|
||||
> 💡 加载器既支持上述转换后的 diffusers 布局,也支持*原始的* MiniMax-H3 分片布局(如 `MiniMax-H3/FL2VA`);原始分片会在加载时在线转换,不会在磁盘上产生中间副本。
|
||||
@@ -233,7 +233,7 @@ accelerate launch --mixed_precision="bf16" --use_fsdp --fsdp_auto_wrap_policy TR
|
||||
--low_vram \
|
||||
--trainable_modules "." \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
### 3.3 常用训练参数
|
||||
@@ -272,8 +272,8 @@ accelerate launch --mixed_precision="bf16" --use_fsdp --fsdp_auto_wrap_policy TR
|
||||
| `--enable_bucket` | 开启 bucket 训练:按分辨率分组训练完整视频,不做中心裁剪 | - |
|
||||
| `--uniform_sampling` | 均匀时间步采样 | - |
|
||||
| `--low_vram` | VAE 与条件器常驻 CPU,仅在编码时移上 GPU | - |
|
||||
| `--train_mode` | `t2v`(纯文本)或 `fl2v`(首帧 keyframe 条件,keyframe 取自训练样本自身) | `fl2v` |
|
||||
| `--t2v_ratio` | 在 `--train_mode=fl2v` 下,按该比例的步数丢弃 keyframe 改训 t2v,使一次训练同时保留两种条件。取值须在 [0, 1] 内且仅适用于 fl2v;0 表示纯 fl2v | 0.25 |
|
||||
| `--train_mode` | `t2v`(纯文本)或 `fl2va`(首帧 keyframe 条件,keyframe 取自训练样本自身) | `fl2va` |
|
||||
| `--t2v_ratio` | 在 `--train_mode=fl2va` 下,按该比例的步数丢弃 keyframe 改训 t2v,使一次训练同时保留两种条件。取值须在 [0, 1] 内且仅适用于 fl2va;0 表示纯 fl2va | 0.25 |
|
||||
| `--resume_from_checkpoint` | 从 checkpoint 路径恢复训练,使用 `"latest"` 自动选择最新 | 无 |
|
||||
| `--trainable_modules` | 可训练模块(`"."` 表示全部模块) | `"."` |
|
||||
| `--validation_steps` | 每 N 步执行一次验证 | 2000 |
|
||||
@@ -350,7 +350,7 @@ accelerate launch --use_deepspeed --deepspeed_config_file config/zero_stage2_con
|
||||
--low_vram \
|
||||
--trainable_modules "." \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
### 3.6 不使用 DeepSpeed 或 FSDP 训练
|
||||
@@ -398,7 +398,7 @@ accelerate launch --mixed_precision="bf16" scripts/minimax_h3/train.py \
|
||||
--low_vram \
|
||||
--trainable_modules "." \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
### 3.7 多机分布式训练
|
||||
@@ -456,7 +456,7 @@ accelerate launch --mixed_precision="bf16" --main_process_ip=$MASTER_ADDR --main
|
||||
--low_vram \
|
||||
--trainable_modules "." \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
```
|
||||
|
||||
**机器 1(Worker)**:
|
||||
|
||||
+83
-48
@@ -2,7 +2,7 @@
|
||||
# scaffold (parameter set, trainable modules, EMA, abnormal gradient clip, checkpointing).
|
||||
#
|
||||
# Full finetuning of the packed-sequence transformer on the *video and audio* rows together, covering `t2v`
|
||||
# (text only), `fl2v` (first-frame keyframe conditioning, the keyframe taken from the training sample itself)
|
||||
# (text only), `fl2va` (first-frame keyframe conditioning, the keyframe taken from the training sample itself)
|
||||
# and `ref2va` (reference image / video / audio conditioning, loaded from `transformer_ref`).
|
||||
# The layout mirrors `scripts/ltx2.3/train.py`: batch-level training (bs=1, the packed layout is per-sample),
|
||||
# video + audio flow-matching loss weighted 0.5 / 0.5, FSDP + offload composable.
|
||||
@@ -18,7 +18,7 @@
|
||||
# Usage:
|
||||
# accelerate launch scripts/minimax_h3/train.py \
|
||||
# --pretrained_model_name_or_path=/root/MiniMax-H3 \
|
||||
# --train_mode=fl2v --gradient_checkpointing --low_vram --trainable_modules "."
|
||||
# --train_mode=fl2va --gradient_checkpointing --low_vram --trainable_modules "."
|
||||
|
||||
import argparse
|
||||
import gc
|
||||
@@ -53,7 +53,6 @@ from packaging import version
|
||||
from PIL import Image
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -82,6 +81,8 @@ from videox_fun.pipeline.pipeline_minimax_h3 import (
|
||||
normalize_ref2va_references, patchify_video_latents, prepare_keyframe_image,
|
||||
ref2va_condition_rows, video_latent_num_frames)
|
||||
from videox_fun.utils import MiniMaxH3Scheduler
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import save_videos_grid
|
||||
|
||||
# Silences diffusers' `randn_tensor` notice about CPU generators producing CUDA tensors (the tensor is created
|
||||
@@ -471,7 +472,7 @@ def log_validation(
|
||||
|
||||
|
||||
def parse_args():
|
||||
parser = argparse.ArgumentParser(description="MiniMax-H3 training (video + audio, t2v / fl2v / ref2va).")
|
||||
parser = argparse.ArgumentParser(description="MiniMax-H3 training (video + audio, t2v / fl2va / ref2va).")
|
||||
parser.add_argument(
|
||||
"--pretrained_model_name_or_path",
|
||||
type=str,
|
||||
@@ -746,16 +747,16 @@ def parse_args():
|
||||
parser.add_argument(
|
||||
"--train_mode",
|
||||
type=str,
|
||||
default="fl2v",
|
||||
choices=["t2v", "fl2v", "ref2va"],
|
||||
help="t2v (text only), fl2v (first-frame keyframe conditioning), or ref2va (reference to video+audio).",
|
||||
default="fl2va",
|
||||
choices=["t2v", "fl2va", "ref2va"],
|
||||
help="t2v (text only), fl2va (first-frame keyframe conditioning), or ref2va (reference to video+audio).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--t2v_ratio",
|
||||
type=float,
|
||||
default=0.0,
|
||||
help=("Under --train_mode=fl2v, the fraction of steps that drop the keyframe and train t2v instead, so one "
|
||||
"run keeps both conditionings. 0 trains fl2v only."),
|
||||
help=("Under --train_mode=fl2va, the fraction of steps that drop the keyframe and train t2v instead, so one "
|
||||
"run keeps both conditionings. 0 trains fl2va only."),
|
||||
)
|
||||
parser.add_argument(
|
||||
"--video_loss_weight",
|
||||
@@ -843,8 +844,8 @@ def parse_args():
|
||||
def main():
|
||||
args = parse_args()
|
||||
|
||||
if args.train_mode not in ("t2v", "fl2v", "ref2va"):
|
||||
raise ValueError(f"`train_mode` must be 't2v', 'fl2v' or 'ref2va', got {args.train_mode!r}.")
|
||||
if args.train_mode not in ("t2v", "fl2va", "ref2va"):
|
||||
raise ValueError(f"`train_mode` must be 't2v', 'fl2va' or 'ref2va', got {args.train_mode!r}.")
|
||||
if args.video_sample_size % 32:
|
||||
raise ValueError(
|
||||
f"`video_sample_size` {args.video_sample_size} must be a multiple of 32: the canvas is patched "
|
||||
@@ -1028,13 +1029,19 @@ def main():
|
||||
# Create EMA for the transformer.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer = MiniMaxH3Transformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer"
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer = EMAModel(ema_transformer.parameters(), model_cls=MiniMaxH3Transformer3DModel, model_config=ema_transformer.config)
|
||||
ema_module = MiniMaxH3Transformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer = FSDPEMA(ema_module, source=transformer, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer = EMAModel(ema_module.parameters(), model_cls=MiniMaxH3Transformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# ------------------------------------------------------------------ save / load hooks
|
||||
# `accelerate` 0.16.0+ supports custom saving hooks; the full transformer is serialized in the diffusers
|
||||
@@ -1075,8 +1082,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -1104,6 +1116,7 @@ def main():
|
||||
_, ema_kwargs = MiniMaxH3Transformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = MiniMaxH3Transformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=MiniMaxH3Transformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -1118,7 +1131,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = MiniMaxH3Transformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1561,7 +1575,7 @@ def main():
|
||||
train_generator = torch.Generator(device="cpu")
|
||||
if args.seed is not None:
|
||||
train_generator.manual_seed(args.seed)
|
||||
# The t2v / fl2v draw of a mixed run gets its own generator, seeded per rank (mirroring `log_validation`) so the
|
||||
# The t2v / fl2va draw of a mixed run gets its own generator, seeded per rank (mirroring `log_validation`) so the
|
||||
# ranks of one global batch do not all land on the same conditioning and every step mixes the two.
|
||||
mode_generator = torch.Generator(device="cpu")
|
||||
if args.seed is not None:
|
||||
@@ -1623,7 +1637,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1702,13 +1716,13 @@ def main():
|
||||
if args.low_vram:
|
||||
target_latents = target_latents.cpu()
|
||||
|
||||
# The fl2v keyframe is the sample's own first frame, prepared onto the canvas exactly like
|
||||
# The fl2va keyframe is the sample's own first frame, prepared onto the canvas exactly like
|
||||
# inference does (stretch: it is the geometry anchor). The keyframe image is a CPU-side PIL
|
||||
# conversion, so the video VAE stays idle on GPU for a moment under `low_vram`.
|
||||
keyframe, keyframe_anchors = None, ()
|
||||
step_mode = args.train_mode
|
||||
references = None
|
||||
if step_mode == "fl2v" and args.t2v_ratio > 0.0:
|
||||
if step_mode == "fl2va" and args.t2v_ratio > 0.0:
|
||||
if float(torch.rand((), generator=mode_generator)) < args.t2v_ratio:
|
||||
step_mode = "t2v"
|
||||
elif step_mode == "ref2va":
|
||||
@@ -1721,14 +1735,14 @@ def main():
|
||||
references = normalize_ref2va_references(references, num_frames, audio_sr)
|
||||
else:
|
||||
step_mode = "t2v"
|
||||
if step_mode == "fl2v":
|
||||
if step_mode == "fl2va":
|
||||
keyframe = Image.fromarray(
|
||||
(pixel_values[0].cpu().permute(1, 2, 0).numpy() * 255).clip(0, 255).astype(np.uint8)
|
||||
).convert("RGB")
|
||||
keyframe = prepare_keyframe_image(keyframe, height, width, stretch=True)
|
||||
keyframe_anchors = ("first",)
|
||||
|
||||
# The conditioner reads `hidden_states[50]` of Qwen3-VL; the presentation of an `fl2v` request
|
||||
# The conditioner reads `hidden_states[50]` of Qwen3-VL; the presentation of an `fl2va` request
|
||||
# carries the keyframe's vision block ahead of the prompt, tagged as video rows. An FSDP-sharded
|
||||
# text encoder tolerates symmetric `.to` moves, so it is brought on-device right before the encode
|
||||
# and back to CPU afterwards.
|
||||
@@ -2057,21 +2071,31 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer.store(transformer.parameters())
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer.restore(transformer.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer.store(transformer.parameters())
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer.restore(transformer.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -2080,26 +2104,37 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer.store(transformer.parameters())
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer.restore(transformer.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer.store(transformer.parameters())
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer.restore(transformer.parameters())
|
||||
|
||||
if global_step >= args.max_train_steps:
|
||||
break
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer = unwrap_model(transformer)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -39,4 +39,4 @@ accelerate launch --mixed_precision="bf16" --use_fsdp \
|
||||
--low_vram \
|
||||
--trainable_modules "." \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
|
||||
@@ -2,7 +2,7 @@
|
||||
# scaffold (parameter set, peft/kohya LoRA switch, comfyui-compatible save, sanity check, checkpointing).
|
||||
#
|
||||
# LoRA finetuning of the packed-sequence transformer on the *video and audio* rows together, covering `t2v`
|
||||
# (text only), `fl2v` (first-frame keyframe conditioning, the keyframe taken from the training sample itself)
|
||||
# (text only), `fl2va` (first-frame keyframe conditioning, the keyframe taken from the training sample itself)
|
||||
# and `ref2va` (reference image / video / audio conditioning, loaded from `transformer_ref`).
|
||||
# The layout mirrors `scripts/ltx2.3/train_lora.py`: batch-level training (bs=1, the packed layout is per-sample),
|
||||
# video + audio flow-matching loss weighted 0.5 / 0.5, FSDP + offload composable.
|
||||
@@ -18,7 +18,7 @@
|
||||
# Usage:
|
||||
# accelerate launch scripts/minimax_h3/train_lora.py \
|
||||
# --pretrained_model_name_or_path=/root/MiniMax-H3 \
|
||||
# --train_mode=fl2v --gradient_checkpointing --low_vram
|
||||
# --train_mode=fl2va --gradient_checkpointing --low_vram
|
||||
|
||||
import argparse
|
||||
import gc
|
||||
@@ -51,7 +51,6 @@ from diffusers.utils.torch_utils import is_compiled_module
|
||||
from packaging import version
|
||||
from PIL import Image
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -81,6 +80,7 @@ from videox_fun.pipeline.pipeline_minimax_h3 import (
|
||||
ref2va_condition_rows, video_latent_num_frames)
|
||||
from videox_fun.utils import MiniMaxH3Scheduler
|
||||
from videox_fun.utils.lora_utils import convert_peft_lora_to_kohya_lora, create_network
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import save_videos_grid
|
||||
|
||||
# Silences diffusers' `randn_tensor` notice about CPU generators producing CUDA tensors (the tensor is created
|
||||
@@ -447,7 +447,7 @@ def log_validation(
|
||||
|
||||
|
||||
def parse_args():
|
||||
parser = argparse.ArgumentParser(description="MiniMax-H3 LoRA training (video + audio, t2v / fl2v / ref2va).")
|
||||
parser = argparse.ArgumentParser(description="MiniMax-H3 LoRA training (video + audio, t2v / fl2va / ref2va).")
|
||||
parser.add_argument(
|
||||
"--pretrained_model_name_or_path",
|
||||
type=str,
|
||||
@@ -724,16 +724,16 @@ def parse_args():
|
||||
parser.add_argument(
|
||||
"--train_mode",
|
||||
type=str,
|
||||
default="fl2v",
|
||||
choices=["t2v", "fl2v", "ref2va"],
|
||||
help="t2v (text only), fl2v (first-frame keyframe conditioning), or ref2va (reference to video+audio).",
|
||||
default="fl2va",
|
||||
choices=["t2v", "fl2va", "ref2va"],
|
||||
help="t2v (text only), fl2va (first-frame keyframe conditioning), or ref2va (reference to video+audio).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--t2v_ratio",
|
||||
type=float,
|
||||
default=0.0,
|
||||
help=("Under --train_mode=fl2v, the fraction of steps that drop the keyframe and train t2v instead, so one "
|
||||
"run keeps both conditionings. 0 trains fl2v only."),
|
||||
help=("Under --train_mode=fl2va, the fraction of steps that drop the keyframe and train t2v instead, so one "
|
||||
"run keeps both conditionings. 0 trains fl2va only."),
|
||||
)
|
||||
parser.add_argument(
|
||||
"--video_loss_weight",
|
||||
@@ -826,13 +826,13 @@ def parse_args():
|
||||
def main():
|
||||
args = parse_args()
|
||||
|
||||
if args.train_mode not in ("t2v", "fl2v", "ref2va"):
|
||||
raise ValueError(f"`train_mode` must be 't2v', 'fl2v' or 'ref2va', got {args.train_mode!r}.")
|
||||
if args.train_mode not in ("t2v", "fl2va", "ref2va"):
|
||||
raise ValueError(f"`train_mode` must be 't2v', 'fl2va' or 'ref2va', got {args.train_mode!r}.")
|
||||
if not 0.0 <= args.t2v_ratio <= 1.0:
|
||||
raise ValueError(f"`t2v_ratio` is a probability and must be in [0, 1], got {args.t2v_ratio}.")
|
||||
if args.t2v_ratio > 0.0 and args.train_mode != "fl2v":
|
||||
if args.t2v_ratio > 0.0 and args.train_mode != "fl2va":
|
||||
raise ValueError(
|
||||
f"`t2v_ratio` mixes t2v steps into an fl2v run, so it only applies to `--train_mode=fl2v`, but "
|
||||
f"`t2v_ratio` mixes t2v steps into an fl2va run, so it only applies to `--train_mode=fl2va`, but "
|
||||
f"`train_mode` is {args.train_mode!r}. Drop `--t2v_ratio` to train {args.train_mode} only."
|
||||
)
|
||||
if args.video_sample_size % 32:
|
||||
@@ -1542,7 +1542,7 @@ def main():
|
||||
train_generator = torch.Generator(device="cpu")
|
||||
if args.seed is not None:
|
||||
train_generator.manual_seed(args.seed)
|
||||
# The t2v / fl2v draw of a mixed run gets its own generator, seeded per rank (mirroring `log_validation`) so the
|
||||
# The t2v / fl2va draw of a mixed run gets its own generator, seeded per rank (mirroring `log_validation`) so the
|
||||
# ranks of one global batch do not all land on the same conditioning and every step mixes the two.
|
||||
mode_generator = torch.Generator(device="cpu")
|
||||
if args.seed is not None:
|
||||
@@ -1672,7 +1672,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1753,16 +1753,16 @@ def main():
|
||||
if args.low_vram:
|
||||
target_latents = target_latents.cpu()
|
||||
|
||||
# The fl2v keyframe is the sample's own first frame, prepared onto the canvas exactly like
|
||||
# The fl2va keyframe is the sample's own first frame, prepared onto the canvas exactly like
|
||||
# inference does (stretch: it is the geometry anchor). The keyframe image is a CPU-side PIL
|
||||
# conversion, so the video VAE stays idle on GPU for a moment under `low_vram`.
|
||||
# `--t2v_ratio` drops the keyframe on that fraction of steps: without the keyframe the presentation
|
||||
# loses its vision block and the packed sequence loses its condition rows, which is exactly a t2v
|
||||
# step, so one run can hold on to both conditionings instead of drifting to fl2v alone.
|
||||
# step, so one run can hold on to both conditionings instead of drifting to fl2va alone.
|
||||
keyframe, keyframe_anchors = None, ()
|
||||
step_mode = args.train_mode
|
||||
references = None
|
||||
if step_mode == "fl2v" and args.t2v_ratio > 0.0:
|
||||
if step_mode == "fl2va" and args.t2v_ratio > 0.0:
|
||||
if float(torch.rand((), generator=mode_generator)) < args.t2v_ratio:
|
||||
step_mode = "t2v"
|
||||
elif step_mode == "ref2va":
|
||||
@@ -1775,14 +1775,14 @@ def main():
|
||||
references = normalize_ref2va_references(references, num_frames, audio_sr)
|
||||
else:
|
||||
step_mode = "t2v"
|
||||
if step_mode == "fl2v":
|
||||
if step_mode == "fl2va":
|
||||
keyframe = Image.fromarray(
|
||||
(pixel_values[0].cpu().permute(1, 2, 0).numpy() * 255).clip(0, 255).astype(np.uint8)
|
||||
).convert("RGB")
|
||||
keyframe = prepare_keyframe_image(keyframe, height, width, stretch=True)
|
||||
keyframe_anchors = ("first",)
|
||||
|
||||
# The conditioner reads `hidden_states[50]` of Qwen3-VL; the presentation of an `fl2v` request
|
||||
# The conditioner reads `hidden_states[50]` of Qwen3-VL; the presentation of an `fl2va` request
|
||||
# carries the keyframe's vision block ahead of the prompt, tagged as video rows. An FSDP-sharded
|
||||
# text encoder tolerates symmetric `.to` moves, so it is brought on-device right before the encode
|
||||
# and back to CPU afterwards.
|
||||
@@ -2083,30 +2083,40 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -2115,14 +2125,20 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
|
||||
if global_step >= args.max_train_steps:
|
||||
break
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -43,4 +43,4 @@ accelerate launch --mixed_precision="bf16" --use_fsdp \
|
||||
--low_vram \
|
||||
--target_name="to_q,to_k,to_v,ff.0,ff.2,proj_in,audio_proj_in,context_embedder" \
|
||||
--t2v_ratio=0.25 \
|
||||
--train_mode="fl2v"
|
||||
--train_mode="fl2va"
|
||||
@@ -67,7 +67,6 @@ from diffusers.optimization import get_scheduler
|
||||
from diffusers.training_utils import EMAModel
|
||||
from diffusers.utils.torch_utils import is_compiled_module
|
||||
from packaging import version
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -101,6 +100,7 @@ from videox_fun.pipeline.pipeline_minimax_h3 import (
|
||||
check_ref2va_references, normalize_ref2va_references,
|
||||
patchify_video_latents, video_latent_num_frames)
|
||||
from videox_fun.utils import MiniMaxH3Scheduler
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import save_videos_with_audio_grid
|
||||
|
||||
# The on-the-fly route (without `--enable_preprocess_training`) encodes conditioning with the canonical MiniMax-H3
|
||||
@@ -1562,7 +1562,7 @@ def main():
|
||||
if ema is not None:
|
||||
ema.to(device)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1684,75 +1684,82 @@ def main():
|
||||
step_started = time.time()
|
||||
|
||||
if global_step % args.checkpointing_steps == 0:
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
# _before_ saving state, check if this save would set us over the `checkpoints_total_limit`
|
||||
if args.checkpoints_total_limit is not None:
|
||||
checkpoints = os.listdir(args.output_dir)
|
||||
checkpoints = [d for d in checkpoints if d.startswith("checkpoint")]
|
||||
checkpoints = sorted(checkpoints, key=lambda x: int(x.split("-")[1]))
|
||||
with progress_bar.paused():
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
# _before_ saving state, check if this save would set us over the `checkpoints_total_limit`
|
||||
if args.checkpoints_total_limit is not None:
|
||||
checkpoints = os.listdir(args.output_dir)
|
||||
checkpoints = [d for d in checkpoints if d.startswith("checkpoint")]
|
||||
checkpoints = sorted(checkpoints, key=lambda x: int(x.split("-")[1]))
|
||||
|
||||
# before we save the new checkpoint, we need to have at _most_ `checkpoints_total_limit - 1` checkpoints
|
||||
if len(checkpoints) >= args.checkpoints_total_limit:
|
||||
num_to_remove = len(checkpoints) - args.checkpoints_total_limit + 1
|
||||
removing_checkpoints = checkpoints[0:num_to_remove]
|
||||
|
||||
logger.info(
|
||||
f"{len(checkpoints)} checkpoints already exist, removing {len(removing_checkpoints)} checkpoints"
|
||||
)
|
||||
logger.info(f"removing checkpoints: {', '.join(removing_checkpoints)}")
|
||||
logger.info(
|
||||
f"{len(checkpoints)} checkpoints already exist, removing {len(removing_checkpoints)} checkpoints"
|
||||
)
|
||||
logger.info(f"removing checkpoints: {', '.join(removing_checkpoints)}")
|
||||
|
||||
for removing_checkpoint in removing_checkpoints:
|
||||
removing_checkpoint = os.path.join(args.output_dir, removing_checkpoint)
|
||||
shutil.rmtree(removing_checkpoint)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
if args.use_deepspeed or args.use_fsdp or args.save_state:
|
||||
accelerator.save_state(save_path)
|
||||
else:
|
||||
save_resume_state(save_path, student, optimizer, lr_scheduler, ema, accelerator)
|
||||
dump_pdd_config(args, save_path)
|
||||
|
||||
if ema is not None:
|
||||
ema.store(trainable_params)
|
||||
ema.copy_to(trainable_params)
|
||||
checkpoint_dir = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
if args.use_deepspeed or args.use_fsdp:
|
||||
state_dict = gather_full_state_dict(transformer, accelerator)
|
||||
if accelerator.is_main_process and state_dict is not None:
|
||||
save_pdd_weights(
|
||||
os.path.join(checkpoint_dir, PDD_EMA_WEIGHTS_NAME),
|
||||
pdd_state_dict(unwrap_model(transformer), state_dict),
|
||||
)
|
||||
dump_pdd_config(args, checkpoint_dir)
|
||||
elif accelerator.is_main_process:
|
||||
save_pdd_weights(
|
||||
os.path.join(checkpoint_dir, PDD_EMA_WEIGHTS_NAME),
|
||||
pdd_state_dict(unwrap_model(transformer), state_dict),
|
||||
pdd_state_dict(unwrap_model(transformer)),
|
||||
)
|
||||
dump_pdd_config(args, checkpoint_dir)
|
||||
elif accelerator.is_main_process:
|
||||
save_pdd_weights(
|
||||
os.path.join(checkpoint_dir, PDD_EMA_WEIGHTS_NAME),
|
||||
pdd_state_dict(unwrap_model(transformer)),
|
||||
)
|
||||
ema.restore(trainable_params)
|
||||
if accelerator.is_main_process:
|
||||
logger.info(f"Saved state to {os.path.join(args.output_dir, f'checkpoint-{global_step}')}")
|
||||
accelerator.wait_for_everyone()
|
||||
ema.restore(trainable_params)
|
||||
if accelerator.is_main_process:
|
||||
logger.info(f"Saved state to {os.path.join(args.output_dir, f'checkpoint-{global_step}')}")
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
if global_step % args.validation_steps == 0 and val_cache:
|
||||
if ema is not None:
|
||||
ema.store(trainable_params)
|
||||
ema.copy_to(trainable_params)
|
||||
accelerator.wait_for_everyone()
|
||||
log_validation(
|
||||
vae, audio_vae, transformer, scheduler, audio_scheduler, args, accelerator,
|
||||
val_cache, grids, global_step,
|
||||
)
|
||||
accelerator.wait_for_everyone()
|
||||
if ema is not None:
|
||||
ema.restore(trainable_params)
|
||||
step_started = time.time()
|
||||
with progress_bar.paused():
|
||||
if ema is not None:
|
||||
ema.store(trainable_params)
|
||||
ema.copy_to(trainable_params)
|
||||
accelerator.wait_for_everyone()
|
||||
log_validation(
|
||||
vae, audio_vae, transformer, scheduler, audio_scheduler, args, accelerator,
|
||||
val_cache, grids, global_step,
|
||||
)
|
||||
accelerator.wait_for_everyone()
|
||||
if ema is not None:
|
||||
ema.restore(trainable_params)
|
||||
step_started = time.time()
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -189,7 +189,7 @@ export DATASET_META_NAME="/mnt/data/metadata.json"
|
||||
mkdir -p models/Diffusion_Transformer
|
||||
|
||||
# Download MiniMax-H3 official weights
|
||||
hf download MiniMax-AI/MiniMax-H3 --local-dir models/Diffusion_Transformer/MiniMax-H3
|
||||
hf download MiniMaxAI/MiniMax-H3 --local-dir models/Diffusion_Transformer/MiniMax-H3
|
||||
|
||||
# Download the pretrained control branch (Controlnet-Union) weights
|
||||
modelscope download --model PAI/MiniMax-H3-Fun-Controlnet-Union --local_dir models/Diffusion_Transformer/MiniMax-H3-Fun-Controlnet-Union
|
||||
|
||||
@@ -189,7 +189,7 @@ export DATASET_META_NAME="/mnt/data/metadata.json"
|
||||
mkdir -p models/Diffusion_Transformer
|
||||
|
||||
# 下载 MiniMax-H3 官方权重
|
||||
hf download MiniMax-AI/MiniMax-H3 --local-dir models/Diffusion_Transformer/MiniMax-H3
|
||||
hf download MiniMaxAI/MiniMax-H3 --local-dir models/Diffusion_Transformer/MiniMax-H3
|
||||
|
||||
# 下载预训练控制分支(Controlnet-Union)权重
|
||||
modelscope download --model PAI/MiniMax-H3-Fun-Controlnet-Union --local_dir models/Diffusion_Transformer/MiniMax-H3-Fun-Controlnet-Union
|
||||
|
||||
@@ -56,9 +56,9 @@ from diffusers.utils.torch_utils import is_compiled_module
|
||||
from einops import rearrange
|
||||
from omegaconf import OmegaConf
|
||||
from packaging import version
|
||||
from PIL import Image
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -89,6 +89,8 @@ from videox_fun.pipeline.pipeline_minimax_h3 import (
|
||||
video_latent_num_frames)
|
||||
from videox_fun.pipeline import MiniMaxH3ControlPipeline
|
||||
from videox_fun.utils import MiniMaxH3Scheduler
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (get_video_to_video_latent,
|
||||
save_videos_grid,
|
||||
save_videos_with_audio_grid)
|
||||
@@ -818,6 +820,13 @@ def main():
|
||||
**transformer_load_kwargs,
|
||||
)
|
||||
|
||||
# The inpaint recipe flag rides on the model config (yaml `transformer_additional_kwargs` → `register_to_config`
|
||||
# → the checkpoint's config.json), so the training loop zeroes the masked pixels exactly the way the inference
|
||||
# pipeline of this checkpoint will; configs predating the key fall back to the legacy recipe.
|
||||
inpaint_masked_pixel_mode = getattr(transformer.config, "inpaint_masked_pixel_mode", "pre_norm")
|
||||
if args.enable_inpaint:
|
||||
logger.info(f"Inpaint masked pixels zeroed `{inpaint_masked_pixel_mode}`.")
|
||||
|
||||
def deepspeed_zero_init_disabled_context_manager():
|
||||
"""
|
||||
returns either a context list that includes one that will disable zero.Init or an empty context list
|
||||
@@ -914,13 +923,19 @@ def main():
|
||||
# Create EMA for the transformer.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer = MiniMaxH3ControlTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer", **transformer_load_kwargs
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer = EMAModel(ema_transformer.parameters(), model_cls=MiniMaxH3ControlTransformer3DModel, model_config=ema_transformer.config)
|
||||
ema_module = MiniMaxH3ControlTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer", **transformer_load_kwargs,
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer = FSDPEMA(ema_module, source=transformer, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer = EMAModel(ema_module.parameters(), model_cls=MiniMaxH3ControlTransformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# ------------------------------------------------------------------ save / load hooks
|
||||
# `accelerate` 0.16.0+ supports custom saving hooks; the full transformer is serialized in the diffusers
|
||||
@@ -962,8 +977,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -991,6 +1011,7 @@ def main():
|
||||
_, ema_kwargs = MiniMaxH3ControlTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = MiniMaxH3ControlTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=MiniMaxH3ControlTransformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -1005,7 +1026,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = MiniMaxH3ControlTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1275,7 +1297,9 @@ def main():
|
||||
|
||||
# The mask follows WanFun's recipe (scripts/wan2.1_fun/train_lora.py): a random inpaint mask
|
||||
# over the sampled clip, and the masked video (masked pixels zeroed) that the VAE encodes as the
|
||||
# inpaint latents.
|
||||
# inpaint latents. Where the zeroing happens — before or after the normalization — follows the
|
||||
# checkpoint's `inpaint_masked_pixel_mode` at encode time below; this collated copy keeps the
|
||||
# legacy layout so the sanity-check dump stays available either way.
|
||||
if args.enable_inpaint:
|
||||
mask = get_random_mask(pixel_values.size()).float()
|
||||
new_examples["mask_pixel_values"].append(pixel_values * (1 - mask))
|
||||
@@ -1372,6 +1396,8 @@ def main():
|
||||
|
||||
# The mask mirrors scripts/flux2_fun/train_control.py: a random inpaint mask over the sliced
|
||||
# clip, and the masked video (masked pixels zeroed) that the VAE encodes as the inpaint latents.
|
||||
# The zeroing point follows `inpaint_masked_pixel_mode` at encode time below, same as the video
|
||||
# collate above.
|
||||
if args.enable_inpaint:
|
||||
mask = get_random_mask(pixel_values.size()).float()
|
||||
new_examples["mask_pixel_values"].append(pixel_values * (1 - mask))
|
||||
@@ -1551,7 +1577,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1588,7 +1614,15 @@ def main():
|
||||
rescale=False,
|
||||
)
|
||||
if args.enable_inpaint:
|
||||
mask_pixel_value = batch["mask_pixel_values"][idx].cpu()[None].permute(0, 2, 1, 3, 4)
|
||||
if inpaint_masked_pixel_mode == "post_norm":
|
||||
# The model sees mid-gray holes (zero in normalized space), not black ones; mirror
|
||||
# that in the dump instead of the collated pre-normalization zeroing.
|
||||
mask_pixel_value = (
|
||||
batch["pixel_values"][idx] * (1 - batch["mask"][idx])
|
||||
+ 0.5 * batch["mask"][idx]
|
||||
).cpu()[None].permute(0, 2, 1, 3, 4)
|
||||
else:
|
||||
mask_pixel_value = batch["mask_pixel_values"][idx].cpu()[None].permute(0, 2, 1, 3, 4)
|
||||
mask_value = batch["mask"][idx].cpu()[None].permute(0, 2, 1, 3, 4).repeat(1, 3, 1, 1, 1)
|
||||
save_videos_grid(mask_pixel_value, f"{args.output_dir}/sanity_check/{gif_name[:10]}-mask_pixel.mp4", rescale=False)
|
||||
save_videos_grid(mask_value, f"{args.output_dir}/sanity_check/{gif_name[:10]}-mask.mp4", rescale=False)
|
||||
@@ -1632,8 +1666,17 @@ def main():
|
||||
control_pixels = control_pixel_values.to(device).permute(1, 0, 2, 3)[None]
|
||||
control_pixels = (control_pixels - pixel_mean) / pixel_std
|
||||
if args.enable_inpaint:
|
||||
mask_pixels = mask_pixel_values.to(device).permute(1, 0, 2, 3)[None]
|
||||
mask_pixels = (mask_pixels - pixel_mean) / pixel_std
|
||||
if inpaint_masked_pixel_mode == "post_norm":
|
||||
# Wan 2.1's recipe: zero the masked pixels *after* the normalization, so the holes sit at
|
||||
# 0 in the VAE's input space (mid-gray in pixel terms) instead of the legacy
|
||||
# pre-normalization zero that lands near -2 as an extreme dark signal and contaminates
|
||||
# the kept regions through the VAE's receptive field. The normalized target video already
|
||||
# carries the full frames, so mask it in place; the collated `mask_pixel_values` then only
|
||||
# feed the sanity-check dump.
|
||||
mask_pixels = pixels * (1 - mask.to(device).permute(1, 0, 2, 3)[None])
|
||||
else:
|
||||
mask_pixels = mask_pixel_values.to(device).permute(1, 0, 2, 3)[None]
|
||||
mask_pixels = (mask_pixels - pixel_mean) / pixel_std
|
||||
|
||||
# Under `low_vram`, load both VAEs at once and keep them on GPU for the video, control and audio
|
||||
# encodes in one session.
|
||||
@@ -1973,22 +2016,32 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
with restore_frozen_requires_grad(transformer, trainable_module_names, args.use_fsdp):
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
with restore_frozen_requires_grad(transformer, trainable_module_names, args.use_fsdp):
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the transformer parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer.store(transformer.parameters())
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer parameters.
|
||||
ema_transformer.restore(transformer.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the transformer parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer.store(transformer.parameters())
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer parameters.
|
||||
ema_transformer.restore(transformer.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1997,26 +2050,37 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the transformer parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer.store(transformer.parameters())
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer parameters.
|
||||
ema_transformer.restore(transformer.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the transformer parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer.store(transformer.parameters())
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer parameters.
|
||||
ema_transformer.restore(transformer.parameters())
|
||||
|
||||
if global_step >= args.max_train_steps:
|
||||
break
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer = unwrap_model(transformer)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
@@ -58,7 +58,6 @@ from omegaconf import OmegaConf
|
||||
from packaging import version
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
current_file_path = os.path.abspath(__file__)
|
||||
@@ -89,6 +88,8 @@ from videox_fun.pipeline.pipeline_minimax_h3 import (
|
||||
video_latent_num_frames)
|
||||
from videox_fun.pipeline import MiniMaxH3ControlPipeline
|
||||
from videox_fun.utils import MiniMaxH3Scheduler
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (get_video_to_video_latent,
|
||||
save_videos_grid,
|
||||
save_videos_with_audio_grid)
|
||||
@@ -830,6 +831,14 @@ def main():
|
||||
**transformer_load_kwargs,
|
||||
)
|
||||
|
||||
# The inpaint recipe flag rides on the model config (yaml `transformer_additional_kwargs` → `register_to_config`
|
||||
# → the checkpoint's config.json), so the training loop zeroes the masked pixels exactly the way the inference
|
||||
# pipeline of this checkpoint will; configs predating the key fall back to the legacy recipe. The student and the
|
||||
# teacher are the same control model, so reading it off `transformer.config` covers both.
|
||||
inpaint_masked_pixel_mode = getattr(transformer.config, "inpaint_masked_pixel_mode", "pre_norm")
|
||||
if args.enable_inpaint:
|
||||
logger.info(f"Inpaint masked pixels zeroed `{inpaint_masked_pixel_mode}`.")
|
||||
|
||||
def deepspeed_zero_init_disabled_context_manager():
|
||||
"""
|
||||
returns either a context list that includes one that will disable zero.Init or an empty context list
|
||||
@@ -929,13 +938,19 @@ def main():
|
||||
# Create EMA for the transformer.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer = MiniMaxH3ControlTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer", **transformer_load_kwargs
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer = EMAModel(ema_transformer.parameters(), model_cls=MiniMaxH3ControlTransformer3DModel, model_config=ema_transformer.config)
|
||||
ema_module = MiniMaxH3ControlTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="transformer", **transformer_load_kwargs,
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer = FSDPEMA(ema_module, source=transformer, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer = EMAModel(ema_module.parameters(), model_cls=MiniMaxH3ControlTransformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# ------------------------------------------------------------------ save / load hooks
|
||||
# `accelerate` 0.16.0+ supports custom saving hooks; the full transformer is serialized in the diffusers
|
||||
@@ -977,8 +992,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -1006,6 +1026,7 @@ def main():
|
||||
_, ema_kwargs = MiniMaxH3ControlTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = MiniMaxH3ControlTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=MiniMaxH3ControlTransformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -1020,7 +1041,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = MiniMaxH3ControlTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1591,7 +1613,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1628,7 +1650,15 @@ def main():
|
||||
rescale=False,
|
||||
)
|
||||
if args.enable_inpaint:
|
||||
mask_pixel_value = batch["mask_pixel_values"][idx].cpu()[None].permute(0, 2, 1, 3, 4)
|
||||
if inpaint_masked_pixel_mode == "post_norm":
|
||||
# The model sees mid-gray holes (zero in normalized space), not black ones; mirror
|
||||
# that in the dump instead of the collated pre-normalization zeroing.
|
||||
mask_pixel_value = (
|
||||
batch["pixel_values"][idx] * (1 - batch["mask"][idx])
|
||||
+ 0.5 * batch["mask"][idx]
|
||||
).cpu()[None].permute(0, 2, 1, 3, 4)
|
||||
else:
|
||||
mask_pixel_value = batch["mask_pixel_values"][idx].cpu()[None].permute(0, 2, 1, 3, 4)
|
||||
mask_value = batch["mask"][idx].cpu()[None].permute(0, 2, 1, 3, 4).repeat(1, 3, 1, 1, 1)
|
||||
save_videos_grid(mask_pixel_value, f"{args.output_dir}/sanity_check/{gif_name[:10]}-mask_pixel.mp4", rescale=False)
|
||||
save_videos_grid(mask_value, f"{args.output_dir}/sanity_check/{gif_name[:10]}-mask.mp4", rescale=False)
|
||||
@@ -1672,8 +1702,17 @@ def main():
|
||||
control_pixels = control_pixel_values.to(device).permute(1, 0, 2, 3)[None]
|
||||
control_pixels = (control_pixels - pixel_mean) / pixel_std
|
||||
if args.enable_inpaint:
|
||||
mask_pixels = mask_pixel_values.to(device).permute(1, 0, 2, 3)[None]
|
||||
mask_pixels = (mask_pixels - pixel_mean) / pixel_std
|
||||
if inpaint_masked_pixel_mode == "post_norm":
|
||||
# Wan 2.1's recipe: zero the masked pixels *after* the normalization, so the holes sit at
|
||||
# 0 in the VAE's input space (mid-gray in pixel terms) instead of the legacy
|
||||
# pre-normalization zero that lands near -2 as an extreme dark signal and contaminates
|
||||
# the kept regions through the VAE's receptive field. The normalized target video already
|
||||
# carries the full frames, so mask it in place; the collated `mask_pixel_values` then only
|
||||
# feed the sanity-check dump.
|
||||
mask_pixels = pixels * (1 - mask.to(device).permute(1, 0, 2, 3)[None])
|
||||
else:
|
||||
mask_pixels = mask_pixel_values.to(device).permute(1, 0, 2, 3)[None]
|
||||
mask_pixels = (mask_pixels - pixel_mean) / pixel_std
|
||||
|
||||
# Under `low_vram`, load both VAEs at once and keep them on GPU for the video, control and audio
|
||||
# encodes in one session.
|
||||
@@ -2076,22 +2115,32 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
with restore_frozen_requires_grad(transformer, trainable_module_names, args.use_fsdp):
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
with restore_frozen_requires_grad(transformer, trainable_module_names, args.use_fsdp):
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the transformer parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer.store(transformer.parameters())
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer parameters.
|
||||
ema_transformer.restore(transformer.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the transformer parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer.store(transformer.parameters())
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer parameters.
|
||||
ema_transformer.restore(transformer.parameters())
|
||||
|
||||
logs = {"avg_cfg_loss": avg_cfg_loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -2100,26 +2149,37 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the transformer parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer.store(transformer.parameters())
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer parameters.
|
||||
ema_transformer.restore(transformer.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the transformer parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer.store(transformer.parameters())
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
log_validation(
|
||||
vae, audio_vae, text_encoder, tokenizer, processor, transformer,
|
||||
scheduler, audio_scheduler, args, accelerator, weight_dtype, global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer parameters.
|
||||
ema_transformer.restore(transformer.parameters())
|
||||
|
||||
if global_step >= args.max_train_steps:
|
||||
break
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer = unwrap_model(transformer)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer.copy_to(transformer.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
+111
-92
@@ -49,7 +49,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
import datasets
|
||||
@@ -72,6 +71,7 @@ from videox_fun.models import (AutoencoderKLMOVAAudio, AutoencoderKLWan,
|
||||
WanTransformer3DModel)
|
||||
from videox_fun.pipeline import MOVAPipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid,
|
||||
@@ -1100,7 +1100,7 @@ def main():
|
||||
# Create EMA for the components.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
# Create EMA models based on boundary_type and train_components
|
||||
ema_transformer = None
|
||||
@@ -1109,23 +1109,27 @@ def main():
|
||||
if args.boundary_type == "high" or args.boundary_type == "full":
|
||||
if "transformer_2" in components_to_train:
|
||||
ema_transformer_2 = WanTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="video_dit"
|
||||
args.pretrained_model_name_or_path, subfolder="video_dit",
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
if args.boundary_type == "low" or args.boundary_type == "full":
|
||||
if "transformer" in components_to_train:
|
||||
ema_transformer = WanTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="video_dit_2"
|
||||
args.pretrained_model_name_or_path, subfolder="video_dit_2",
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
if "transformer_audio" in components_to_train:
|
||||
ema_transformer_audio = WanAudioTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="audio_dit"
|
||||
args.pretrained_model_name_or_path, subfolder="audio_dit",
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
if "dual_tower_bridge" in components_to_train:
|
||||
ema_dual_tower_bridge = MOVADualTowerConditionalBridge.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="dual_tower_bridge"
|
||||
args.pretrained_model_name_or_path, subfolder="dual_tower_bridge",
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Collect parameters for EMA
|
||||
@@ -1230,13 +1234,13 @@ def main():
|
||||
if args.use_ema:
|
||||
# Load EMA models (only for trained components)
|
||||
if ema_transformer is not None and "transformer" in components_to_train and os.path.exists(os.path.join(input_dir, "ema_transformer")):
|
||||
ema_transformer.from_pretrained(os.path.join(input_dir, "ema_transformer")).to(accelerator.device)
|
||||
ema_transformer.from_pretrained(os.path.join(input_dir, "ema_transformer"), low_cpu_mem_usage=True).to(accelerator.device)
|
||||
if ema_transformer_2 is not None and "transformer_2" in components_to_train and os.path.exists(os.path.join(input_dir, "ema_transformer_2")):
|
||||
ema_transformer_2.from_pretrained(os.path.join(input_dir, "ema_transformer_2")).to(accelerator.device)
|
||||
ema_transformer_2.from_pretrained(os.path.join(input_dir, "ema_transformer_2"), low_cpu_mem_usage=True).to(accelerator.device)
|
||||
if "transformer_audio" in components_to_train and os.path.exists(os.path.join(input_dir, "ema_transformer_audio")):
|
||||
ema_transformer_audio.from_pretrained(os.path.join(input_dir, "ema_transformer_audio")).to(accelerator.device)
|
||||
ema_transformer_audio.from_pretrained(os.path.join(input_dir, "ema_transformer_audio"), low_cpu_mem_usage=True).to(accelerator.device)
|
||||
if "dual_tower_bridge" in components_to_train and os.path.exists(os.path.join(input_dir, "ema_dual_tower_bridge")):
|
||||
ema_dual_tower_bridge.from_pretrained(os.path.join(input_dir, "ema_dual_tower_bridge")).to(accelerator.device)
|
||||
ema_dual_tower_bridge.from_pretrained(os.path.join(input_dir, "ema_dual_tower_bridge"), low_cpu_mem_usage=True).to(accelerator.device)
|
||||
|
||||
for i in range(len(models)):
|
||||
models.pop()
|
||||
@@ -1585,35 +1589,34 @@ def main():
|
||||
|
||||
# Encode prompts when enable_text_encoder_in_dataloader=True
|
||||
if args.enable_text_encoder_in_dataloader:
|
||||
# Gemma expects left padding for chat-style prompts
|
||||
tokenizer.padding_side = "left"
|
||||
# UMT5 tokenizer (T5-style). Kept consistent with the in-loop
|
||||
# encoding path and MOVAPipeline._get_t5_prompt_embeds so that
|
||||
# precomputed embeddings match the single-layer last_hidden_state
|
||||
# that the transformer consumes via `context`.
|
||||
tokenizer.padding_side = "right"
|
||||
if tokenizer.pad_token is None:
|
||||
tokenizer.pad_token = tokenizer.eos_token
|
||||
|
||||
|
||||
cleaned_texts = [whitespace_clean(basic_clean(text)) for text in new_examples['text']]
|
||||
prompt_ids = tokenizer(
|
||||
new_examples['text'],
|
||||
cleaned_texts,
|
||||
max_length=args.tokenizer_max_length,
|
||||
padding="max_length",
|
||||
add_special_tokens=True,
|
||||
truncation=True,
|
||||
return_tensors="pt"
|
||||
)
|
||||
text_encoder_outputs = text_encoder(
|
||||
input_ids=prompt_ids.input_ids,
|
||||
attention_mask=prompt_ids.attention_mask,
|
||||
output_hidden_states=True
|
||||
)
|
||||
text_encoder_hidden_states = text_encoder_outputs.hidden_states
|
||||
text_encoder_hidden_states = torch.stack(text_encoder_hidden_states, dim=-1)
|
||||
|
||||
# Pack text embeddings (normalized and flattened)
|
||||
sequence_lengths = prompt_ids.attention_mask.sum(dim=-1)
|
||||
prompt_embeds = _pack_text_embeds(
|
||||
text_encoder_hidden_states,
|
||||
sequence_lengths,
|
||||
device=text_encoder_hidden_states.device,
|
||||
padding_side=tokenizer.padding_side,
|
||||
scale_factor=8,
|
||||
prompt_attention_mask = prompt_ids.attention_mask
|
||||
seq_lens = prompt_attention_mask.gt(0).sum(dim=1).long()
|
||||
with torch.no_grad():
|
||||
prompt_embeds = text_encoder(
|
||||
input_ids=prompt_ids.input_ids,
|
||||
attention_mask=prompt_attention_mask,
|
||||
).last_hidden_state
|
||||
prompt_embeds = [embed[:seq_len] for embed, seq_len in zip(prompt_embeds, seq_lens)]
|
||||
prompt_embeds = torch.stack(
|
||||
[torch.cat([embed, embed.new_zeros(args.tokenizer_max_length - embed.size(0), embed.size(1))])
|
||||
for embed in prompt_embeds], dim=0
|
||||
)
|
||||
new_examples['encoder_attention_mask'] = prompt_ids.attention_mask
|
||||
new_examples['encoder_hidden_states'] = prompt_embeds
|
||||
@@ -1747,7 +1750,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -2206,40 +2209,50 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Collect all trainable parameters for EMA
|
||||
all_params = []
|
||||
if transformer is not None:
|
||||
all_params.extend(transformer.parameters())
|
||||
if transformer_2 is not None:
|
||||
all_params.extend(transformer_2.parameters())
|
||||
all_params.extend(transformer_audio.parameters())
|
||||
all_params.extend(dual_tower_bridge.parameters())
|
||||
# Store the parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_mova_model.store(all_params)
|
||||
ema_mova_model.copy_to(all_params)
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer,
|
||||
transformer_2,
|
||||
transformer_audio,
|
||||
dual_tower_bridge,
|
||||
mova_model,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original parameters.
|
||||
ema_mova_model.restore(all_params)
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Collect all trainable parameters for EMA
|
||||
all_params = []
|
||||
if transformer is not None:
|
||||
all_params.extend(transformer.parameters())
|
||||
if transformer_2 is not None:
|
||||
all_params.extend(transformer_2.parameters())
|
||||
all_params.extend(transformer_audio.parameters())
|
||||
all_params.extend(dual_tower_bridge.parameters())
|
||||
# Store the parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_mova_model.store(all_params)
|
||||
ema_mova_model.copy_to(all_params)
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer,
|
||||
transformer_2,
|
||||
transformer_audio,
|
||||
dual_tower_bridge,
|
||||
mova_model,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original parameters.
|
||||
ema_mova_model.restore(all_params)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -2248,36 +2261,42 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Collect all trainable parameters for EMA
|
||||
all_params = []
|
||||
if transformer is not None:
|
||||
all_params.extend(transformer.parameters())
|
||||
if transformer_2 is not None:
|
||||
all_params.extend(transformer_2.parameters())
|
||||
all_params.extend(transformer_audio.parameters())
|
||||
all_params.extend(dual_tower_bridge.parameters())
|
||||
# Store the parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_mova_model.store(all_params)
|
||||
ema_mova_model.copy_to(all_params)
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer,
|
||||
transformer_2,
|
||||
transformer_audio,
|
||||
dual_tower_bridge,
|
||||
mova_model,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original parameters.
|
||||
ema_mova_model.restore(all_params)
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Collect all trainable parameters for EMA
|
||||
all_params = []
|
||||
if transformer is not None:
|
||||
all_params.extend(transformer.parameters())
|
||||
if transformer_2 is not None:
|
||||
all_params.extend(transformer_2.parameters())
|
||||
all_params.extend(transformer_audio.parameters())
|
||||
all_params.extend(dual_tower_bridge.parameters())
|
||||
# Store the parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_mova_model.store(all_params)
|
||||
ema_mova_model.copy_to(all_params)
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer,
|
||||
transformer_2,
|
||||
transformer_audio,
|
||||
dual_tower_bridge,
|
||||
mova_model,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original parameters.
|
||||
ema_mova_model.restore(all_params)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
+86
-71
@@ -48,7 +48,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
import datasets
|
||||
@@ -73,6 +72,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid,
|
||||
@@ -1608,35 +1608,34 @@ def main():
|
||||
|
||||
# Encode prompts when enable_text_encoder_in_dataloader=True
|
||||
if args.enable_text_encoder_in_dataloader:
|
||||
# Gemma expects left padding for chat-style prompts
|
||||
tokenizer.padding_side = "left"
|
||||
# UMT5 tokenizer (T5-style). Kept consistent with the in-loop
|
||||
# encoding path and MOVAPipeline._get_t5_prompt_embeds so that
|
||||
# precomputed embeddings match the single-layer last_hidden_state
|
||||
# that the transformer consumes via `context`.
|
||||
tokenizer.padding_side = "right"
|
||||
if tokenizer.pad_token is None:
|
||||
tokenizer.pad_token = tokenizer.eos_token
|
||||
|
||||
|
||||
cleaned_texts = [whitespace_clean(basic_clean(text)) for text in new_examples['text']]
|
||||
prompt_ids = tokenizer(
|
||||
new_examples['text'],
|
||||
cleaned_texts,
|
||||
max_length=args.tokenizer_max_length,
|
||||
padding="max_length",
|
||||
add_special_tokens=True,
|
||||
truncation=True,
|
||||
return_tensors="pt"
|
||||
)
|
||||
text_encoder_outputs = text_encoder(
|
||||
input_ids=prompt_ids.input_ids,
|
||||
attention_mask=prompt_ids.attention_mask,
|
||||
output_hidden_states=True
|
||||
)
|
||||
text_encoder_hidden_states = text_encoder_outputs.hidden_states
|
||||
text_encoder_hidden_states = torch.stack(text_encoder_hidden_states, dim=-1)
|
||||
|
||||
# Pack text embeddings (normalized and flattened)
|
||||
sequence_lengths = prompt_ids.attention_mask.sum(dim=-1)
|
||||
prompt_embeds = _pack_text_embeds(
|
||||
text_encoder_hidden_states,
|
||||
sequence_lengths,
|
||||
device=text_encoder_hidden_states.device,
|
||||
padding_side=tokenizer.padding_side,
|
||||
scale_factor=8,
|
||||
prompt_attention_mask = prompt_ids.attention_mask
|
||||
seq_lens = prompt_attention_mask.gt(0).sum(dim=1).long()
|
||||
with torch.no_grad():
|
||||
prompt_embeds = text_encoder(
|
||||
input_ids=prompt_ids.input_ids,
|
||||
attention_mask=prompt_attention_mask,
|
||||
).last_hidden_state
|
||||
prompt_embeds = [embed[:seq_len] for embed, seq_len in zip(prompt_embeds, seq_lens)]
|
||||
prompt_embeds = torch.stack(
|
||||
[torch.cat([embed, embed.new_zeros(args.tokenizer_max_length - embed.size(0), embed.size(1))])
|
||||
for embed in prompt_embeds], dim=0
|
||||
)
|
||||
new_examples['encoder_attention_mask'] = prompt_ids.attention_mask
|
||||
new_examples['encoder_hidden_states'] = prompt_embeds
|
||||
@@ -1846,7 +1845,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -2281,44 +2280,54 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
# Save peft adapter weights for each component separately
|
||||
for component_name in components_to_train:
|
||||
if component_name in peft_adapters:
|
||||
module = peft_adapters[component_name]
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
# Save peft adapter weights for each component separately
|
||||
for component_name in components_to_train:
|
||||
if component_name in peft_adapters:
|
||||
module = peft_adapters[component_name]
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-{component_name}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(module))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
logger.info(f"Saved {component_name} safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
# Save each component's LoRA weights separately
|
||||
for component_name, network in networks.items():
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-{component_name}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(module))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved {component_name} safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
# Save each component's LoRA weights separately
|
||||
for component_name, network in networks.items():
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-{component_name}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved {component_name} safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer,
|
||||
transformer_2,
|
||||
transformer_audio,
|
||||
dual_tower_bridge,
|
||||
mova_model,
|
||||
networks if not args.use_peft_lora else None,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer,
|
||||
transformer_2,
|
||||
transformer_audio,
|
||||
dual_tower_bridge,
|
||||
mova_model,
|
||||
networks if not args.use_peft_lora else None,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -2327,22 +2336,28 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer,
|
||||
transformer_2,
|
||||
transformer_audio,
|
||||
dual_tower_bridge,
|
||||
mova_model,
|
||||
networks if not args.use_peft_lora else None,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
audio_vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer,
|
||||
transformer_2,
|
||||
transformer_audio,
|
||||
dual_tower_bridge,
|
||||
mova_model,
|
||||
networks if not args.use_peft_lora else None,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
+74
-43
@@ -54,7 +54,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -75,6 +74,8 @@ from videox_fun.models import (AutoencoderKLQwenImage,
|
||||
Qwen2Tokenizer, QwenImageTransformer2DModel)
|
||||
from videox_fun.pipeline import QwenImagePipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -761,6 +762,7 @@ def main():
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -811,15 +813,21 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = QwenImageTransformer2DModel.from_pretrained(
|
||||
ema_module = QwenImageTransformer2DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=QwenImageTransformer2DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=QwenImageTransformer2DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -836,8 +844,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -864,6 +877,7 @@ def main():
|
||||
_, ema_kwargs = QwenImageTransformer2DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = QwenImageTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=QwenImageTransformer2DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -878,7 +892,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = QwenImageTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1283,7 +1298,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1540,27 +1555,37 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1569,23 +1594,29 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -54,7 +54,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -81,6 +80,8 @@ from videox_fun.pipeline.pipeline_qwenimage_edit import (
|
||||
from videox_fun.pipeline.pipeline_qwenimage_edit_plus import (
|
||||
CONDITION_IMAGE_SIZE, VAE_IMAGE_SIZE)
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (get_image, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
@@ -802,6 +803,7 @@ def main():
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -852,15 +854,21 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = QwenImageTransformer2DModel.from_pretrained(
|
||||
ema_module = QwenImageTransformer2DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=QwenImageTransformer2DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=QwenImageTransformer2DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -877,8 +885,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -905,6 +918,7 @@ def main():
|
||||
_, ema_kwargs = QwenImageTransformer2DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = QwenImageTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=QwenImageTransformer2DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -919,7 +933,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = QwenImageTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1337,7 +1352,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1725,28 +1740,38 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1755,24 +1780,30 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -54,7 +54,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -84,6 +83,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (get_image, get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
|
||||
@@ -809,6 +809,7 @@ def main():
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -1386,7 +1387,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1749,38 +1750,48 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1789,18 +1800,24 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
processor,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -51,7 +51,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -74,6 +73,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -765,6 +765,7 @@ def main():
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -1329,7 +1330,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1563,37 +1564,47 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1602,17 +1613,23 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -0,0 +1,591 @@
|
||||
# Qwen-Image 2.1 Full Parameter Training Guide
|
||||
|
||||
This document provides a complete workflow for full parameter training of the Qwen-Image 2.1 Diffusion Transformer, including environment configuration, data preparation, distributed training, and inference testing.
|
||||
---
|
||||
|
||||
## Table of Contents
|
||||
- [1. Environment Configuration](#1-environment-configuration)
|
||||
- [2. Data Preparation](#2-data-preparation)
|
||||
- [2.1 Quick Test Dataset](#21-quick-test-dataset)
|
||||
- [2.2 Dataset Structure](#22-dataset-structure)
|
||||
- [2.3 metadata.json Format](#23-metadatajson-format)
|
||||
- [2.4 Relative vs Absolute Path Usage](#24-relative-vs-absolute-path-usage)
|
||||
- [3. Full Parameter Training](#3-full-parameter-training)
|
||||
- [3.1 Download Pretrained Model](#31-download-pretrained-model)
|
||||
- [3.2 Quick Start (DeepSpeed-Zero-2)](#32-quick-start-deepspeed-zero-2)
|
||||
- [3.3 Common Training Parameters](#33-common-training-parameters)
|
||||
- [3.4 Training Validation](#34-training-validation)
|
||||
- [3.5 Training with FSDP](#35-training-with-fsdp)
|
||||
- [3.6 Other Backends](#36-other-backends)
|
||||
- [3.7 Multi-Machine Distributed Training](#37-multi-machine-distributed-training)
|
||||
- [4. Inference Testing](#4-inference-testing)
|
||||
- [4.1 Inference Parameter Parsing](#41-inference-parameter-parsing)
|
||||
- [4.2 Single GPU Inference](#42-single-gpu-inference)
|
||||
- [4.3 Multi-GPU Parallel Inference](#43-multi-gpu-parallel-inference)
|
||||
- [5. Additional Resources](#5-additional-resources)
|
||||
|
||||
---
|
||||
|
||||
## 1. Environment Configuration
|
||||
|
||||
**Method 1: Using requirements.txt**
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
**Method 2: Manual Dependency Installation**
|
||||
|
||||
```bash
|
||||
pip install Pillow einops safetensors timm tomesd librosa "torch>=2.1.2" torchdiffeq torchsde decord datasets numpy scikit-image
|
||||
pip install omegaconf SentencePiece imageio[ffmpeg] imageio[pyav] tensorboard beautifulsoup4 ftfy func_timeout onnxruntime
|
||||
pip install "peft>=0.17.0" "accelerate>=0.25.0" "gradio>=3.41.2" "diffusers>=0.30.1" "transformers>=4.46.2"
|
||||
pip install yunchang xfuser modelscope openpyxl
|
||||
pip uninstall opencv-python opencv-contrib-python opencv-python-headless -y
|
||||
pip install opencv-python-headless
|
||||
pip install deepspeed==0.17.0 numpy==1.26.4
|
||||
```
|
||||
|
||||
**Method 3: Using Docker**
|
||||
|
||||
When using Docker, please ensure that the GPU driver and CUDA environment are correctly installed on your machine, then execute the following commands:
|
||||
|
||||
```
|
||||
# pull image
|
||||
docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# enter image
|
||||
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## 2. Data Preparation
|
||||
|
||||
### 2.1 Quick Test Dataset
|
||||
|
||||
We provide a test dataset containing several training samples.
|
||||
|
||||
```bash
|
||||
# Download official demo dataset
|
||||
modelscope download --dataset PAI/X-Fun-Images-Demo --local_dir ./datasets/X-Fun-Images-Demo
|
||||
```
|
||||
|
||||
### 2.2 Dataset Structure
|
||||
|
||||
```
|
||||
📦 datasets/
|
||||
├── 📂 my_dataset/
|
||||
│ ├── 📂 train/
|
||||
│ │ ├── 📄 image001.jpg
|
||||
│ │ ├── 📄 image002.png
|
||||
│ │ └── 📄 ...
|
||||
│ └── 📄 metadata.json
|
||||
```
|
||||
|
||||
### 2.3 metadata.json Format
|
||||
|
||||
**Relative Path Format** (example):
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "train/image001.jpg",
|
||||
"text": "A beautiful sunset over the ocean, golden hour lighting",
|
||||
"width": 1024,
|
||||
"height": 1024
|
||||
},
|
||||
{
|
||||
"file_path": "train/image002.png",
|
||||
"text": "Portrait of a young woman, studio lighting, high quality",
|
||||
"width": 1024,
|
||||
"height": 1024
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
**Absolute Path Format**:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "/mnt/data/images/sunset.jpg",
|
||||
"text": "A beautiful sunset over the ocean",
|
||||
"width": 1024,
|
||||
"height": 1024
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
**Key Fields Description**:
|
||||
- `file_path`: Image path (relative or absolute)
|
||||
- `text`: Image description (English prompt)
|
||||
- `width` / `height`: Image dimensions (**recommended** to provide for bucket training; if not provided, they will be automatically read during training, which may slow down training when data is stored on slow systems like OSS)
|
||||
- You can use `scripts/process_json_add_width_and_height.py` to add width and height fields to JSON files without these fields, supporting both images and videos
|
||||
- Usage: `python scripts/process_json_add_width_and_height.py --input_file datasets/X-Fun-Images-Demo/metadata.json --output_file datasets/X-Fun-Images-Demo/metadata_add_width_height.json`
|
||||
|
||||
> 💡 Training images are read as RGB and automatically composited over an opaque alpha channel before VAE encoding, so you do **not** need to provide RGBA data.
|
||||
|
||||
### 2.4 Relative vs Absolute Path Usage
|
||||
|
||||
**Relative Paths**:
|
||||
|
||||
If your data uses relative paths, configure the training script as follows:
|
||||
|
||||
```bash
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
```
|
||||
|
||||
**Absolute Paths**:
|
||||
|
||||
If your data uses absolute paths, configure the training script as follows:
|
||||
|
||||
```bash
|
||||
export DATASET_NAME=""
|
||||
export DATASET_META_NAME="/mnt/data/metadata_add_width_height.json"
|
||||
```
|
||||
|
||||
> 💡 **Recommendation**: If the dataset is small and stored locally, use relative paths. If the dataset is stored on external storage (e.g., NAS, OSS) or shared across multiple machines, use absolute paths.
|
||||
|
||||
---
|
||||
|
||||
## 3. Full Parameter Training
|
||||
|
||||
### 3.1 Download Pretrained Model
|
||||
|
||||
```bash
|
||||
# Create model directory
|
||||
mkdir -p models/Diffusion_Transformer
|
||||
|
||||
# Download Qwen-Image 2.1 official weights
|
||||
modelscope download --model Qwen/Qwen-Image-2.1 --local_dir models/Diffusion_Transformer/Qwen-Image-2.1
|
||||
```
|
||||
|
||||
> 💡 If the ModelScope id differs from the above, adjust it to the official Qwen-Image-2.1 release. You may also point `--pretrained_model_name_or_path` to any local directory in diffusers layout that contains the `transformer/`, `vae/`, `text_encoder/`, `processor/` and `scheduler/` subfolders.
|
||||
|
||||
### 3.2 Quick Start (DeepSpeed-Zero-2)
|
||||
|
||||
If you have downloaded the data as per **2.1 Quick Test Dataset** and the weights as per **3.1 Download Pretrained Model**, you can directly copy and run the quick start command.
|
||||
|
||||
DeepSpeed-Zero-2 and FSDP are recommended for training. Here we use DeepSpeed-Zero-2 as an example.
|
||||
|
||||
The difference between DeepSpeed-Zero-2 and FSDP lies in whether the model weights are sharded. **If VRAM is insufficient when using multiple GPUs with DeepSpeed-Zero-2**, you can switch to FSDP.
|
||||
|
||||
```bash
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
# NCCL_IB_DISABLE=1 and NCCL_P2P_DISABLE=1 are used in multi nodes without RDMA.
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --use_deepspeed --deepspeed_config_file config/zero_stage2_config.json --deepspeed_multinode_launcher standard scripts/qwenimage21/train.py \
|
||||
--pretrained_model_name_or_path=$MODEL_NAME \
|
||||
--train_data_dir=$DATASET_NAME \
|
||||
--train_data_meta=$DATASET_META_NAME \
|
||||
--train_batch_size=1 \
|
||||
--image_sample_size=1024 \
|
||||
--gradient_accumulation_steps=1 \
|
||||
--dataloader_num_workers=8 \
|
||||
--num_train_epochs=100 \
|
||||
--checkpointing_steps=50 \
|
||||
--learning_rate=2e-05 \
|
||||
--lr_scheduler="constant_with_warmup" \
|
||||
--lr_warmup_steps=100 \
|
||||
--seed=42 \
|
||||
--output_dir="output_dir_qwenimage21" \
|
||||
--gradient_checkpointing \
|
||||
--mixed_precision="bf16" \
|
||||
--adam_weight_decay=3e-2 \
|
||||
--adam_epsilon=1e-10 \
|
||||
--vae_mini_batch=1 \
|
||||
--max_grad_norm=0.05 \
|
||||
--enable_bucket \
|
||||
--uniform_sampling \
|
||||
--trainable_modules "."
|
||||
```
|
||||
|
||||
### 3.3 Common Training Parameters
|
||||
|
||||
**Key Parameter Descriptions**:
|
||||
|
||||
| Parameter | Description | Example Value |
|
||||
|-----|------|-------|
|
||||
| `--pretrained_model_name_or_path` | Path to pretrained model | `models/Diffusion_Transformer/Qwen-Image-2.1` |
|
||||
| `--train_data_dir` | Training data directory | `datasets/X-Fun-Images-Demo/` |
|
||||
| `--train_data_meta` | Training data metadata file | `datasets/X-Fun-Images-Demo/metadata_add_width_height.json` |
|
||||
| `--train_batch_size` | Samples per batch | 1 |
|
||||
| `--image_sample_size` | Maximum training resolution, auto bucketing | 1024 |
|
||||
| `--gradient_accumulation_steps` | Gradient accumulation steps (equivalent to larger batch) | 1 |
|
||||
| `--dataloader_num_workers` | DataLoader subprocesses | 8 |
|
||||
| `--num_train_epochs` | Number of training epochs | 100 |
|
||||
| `--checkpointing_steps` | Save checkpoint every N steps | 50 |
|
||||
| `--learning_rate` | Initial learning rate | 2e-05 |
|
||||
| `--lr_scheduler` | Learning rate scheduler | `constant_with_warmup` |
|
||||
| `--lr_warmup_steps` | Learning rate warmup steps | 100 |
|
||||
| `--seed` | Random seed | 42 |
|
||||
| `--output_dir` | Output directory | `output_dir_qwenimage21` |
|
||||
| `--gradient_checkpointing` | Enable activation checkpointing | - |
|
||||
| `--mixed_precision` | Mixed precision: `fp16/bf16` | `bf16` |
|
||||
| `--adam_weight_decay` | AdamW weight decay | 3e-2 |
|
||||
| `--adam_epsilon` | AdamW epsilon value | 1e-10 |
|
||||
| `--vae_mini_batch` | Mini-batch size for VAE encoding | 1 |
|
||||
| `--max_grad_norm` | Gradient clipping threshold | 0.05 |
|
||||
| `--enable_bucket` | Enable bucket training: trains entire images grouped by resolution without center cropping | - |
|
||||
| `--random_hw_adapt` | Auto-scale images to random size in range `[512, image_sample_size]` | - |
|
||||
| `--resume_from_checkpoint` | Resume training from checkpoint path, use `"latest"` to auto-select latest | None |
|
||||
| `--uniform_sampling` | Uniform timestep sampling | - |
|
||||
| `--trainable_modules` | Trainable modules (`"."` means all modules) | `"."` |
|
||||
| `--tokenizer_max_length` | Maximum prompt token length fed to the Qwen3-VL text encoder | 1024 |
|
||||
| `--validation_steps` | Execute validation every N steps | 100 |
|
||||
| `--validation_epochs` | Execute validation every N epochs | 100 |
|
||||
| `--validation_prompts` | Prompts used during validation | `"1girl, black_hair, ..."` |
|
||||
|
||||
|
||||
### 3.4 Training Validation
|
||||
|
||||
You can configure validation parameters to periodically generate test images during training, allowing you to monitor training progress and model quality.
|
||||
|
||||
**Validation Parameters**:
|
||||
|
||||
```bash
|
||||
accelerate launch --use_deepspeed --deepspeed_config_file config/zero_stage2_config.json --deepspeed_multinode_launcher standard scripts/qwenimage21/train.py \
|
||||
# ... (other training parameters)
|
||||
--validation_steps=100 \
|
||||
--validation_epochs=100 \
|
||||
--validation_prompts="1girl, black_hair, brown_eyes, earrings, freckles, grey_background, jewelry, lips, long_hair, looking_at_viewer, nose, piercing, realistic, red_lips, solo, upper_body"
|
||||
```
|
||||
|
||||
**Parameter Descriptions**:
|
||||
|
||||
| Parameter | Description | Recommended Value |
|
||||
|-----------|-------------|-------------------|
|
||||
| `--validation_steps` | Execute validation every N steps. If your dataset is large and you want to save validation time, you can set a larger value (e.g., 100 or 500) | 100 |
|
||||
| `--validation_epochs` | Execute validation every N epochs | 100 |
|
||||
| `--validation_prompts` | Prompt for validation image generation. Use multiple space-separated prompt strings | Space-separated prompt strings |
|
||||
|
||||
**Notes**:
|
||||
- Validation images will be saved to the `output_dir` directory
|
||||
- Setting `--validation_steps=1` means validation is performed every step, which may slow down training. Adjust according to your needs
|
||||
- For multi-prompt validation, use: `--validation_prompts "prompt1" "prompt2" "prompt3"`
|
||||
|
||||
|
||||
### 3.5 Training with FSDP
|
||||
|
||||
**If VRAM is insufficient when using multiple GPUs with DeepSpeed-Zero-2**, you can switch to FSDP. Note that the transformer layer class to wrap for Qwen-Image 2.1 is `QwenImage21TransformerBlock`.
|
||||
|
||||
```sh
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
# NCCL_IB_DISABLE=1 and NCCL_P2P_DISABLE=1 are used in multi nodes without RDMA.
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --mixed_precision="bf16" --use_fsdp --fsdp_auto_wrap_policy TRANSFORMER_BASED_WRAP --fsdp_transformer_layer_cls_to_wrap=QwenImage21TransformerBlock --fsdp_sharding_strategy "FULL_SHARD" --fsdp_state_dict_type=SHARDED_STATE_DICT --fsdp_backward_prefetch "BACKWARD_PRE" --fsdp_cpu_ram_efficient_loading False scripts/qwenimage21/train.py \
|
||||
--pretrained_model_name_or_path=$MODEL_NAME \
|
||||
--train_data_dir=$DATASET_NAME \
|
||||
--train_data_meta=$DATASET_META_NAME \
|
||||
--train_batch_size=1 \
|
||||
--image_sample_size=1024 \
|
||||
--gradient_accumulation_steps=1 \
|
||||
--dataloader_num_workers=8 \
|
||||
--num_train_epochs=100 \
|
||||
--checkpointing_steps=50 \
|
||||
--learning_rate=2e-05 \
|
||||
--lr_scheduler="constant_with_warmup" \
|
||||
--lr_warmup_steps=100 \
|
||||
--seed=42 \
|
||||
--output_dir="output_dir_qwenimage21" \
|
||||
--gradient_checkpointing \
|
||||
--mixed_precision="bf16" \
|
||||
--adam_weight_decay=3e-2 \
|
||||
--adam_epsilon=1e-10 \
|
||||
--vae_mini_batch=1 \
|
||||
--max_grad_norm=0.05 \
|
||||
--enable_bucket \
|
||||
--uniform_sampling \
|
||||
--trainable_modules "."
|
||||
```
|
||||
|
||||
### 3.6 Other Backends
|
||||
|
||||
#### 3.6.1 Training with DeepSpeed-Zero-3
|
||||
|
||||
DeepSpeed Zero-3 is not highly recommended at the moment. In this repository, using FSDP has fewer errors and is more stable.
|
||||
|
||||
DeepSpeed Zero-3:
|
||||
|
||||
After training, you can use the following command to get the final model:
|
||||
|
||||
```sh
|
||||
python scripts/zero_to_bf16.py output_dir/checkpoint-{our-num-steps} output_dir/checkpoint-{your-num-steps}-outputs --max_shard_size 80GB --safe_serialization
|
||||
```
|
||||
|
||||
Training shell command:
|
||||
```sh
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
# NCCL_IB_DISABLE=1 and NCCL_P2P_DISABLE=1 are used in multi nodes without RDMA.
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --zero_stage 3 --zero3_save_16bit_model true --zero3_init_flag true --use_deepspeed --deepspeed_config_file config/zero_stage3_config.json --deepspeed_multinode_launcher standard scripts/qwenimage21/train.py \
|
||||
--pretrained_model_name_or_path=$MODEL_NAME \
|
||||
--train_data_dir=$DATASET_NAME \
|
||||
--train_data_meta=$DATASET_META_NAME \
|
||||
--train_batch_size=1 \
|
||||
--image_sample_size=1024 \
|
||||
--gradient_accumulation_steps=1 \
|
||||
--dataloader_num_workers=8 \
|
||||
--num_train_epochs=100 \
|
||||
--checkpointing_steps=50 \
|
||||
--learning_rate=2e-05 \
|
||||
--lr_scheduler="constant_with_warmup" \
|
||||
--lr_warmup_steps=100 \
|
||||
--seed=42 \
|
||||
--output_dir="output_dir_qwenimage21" \
|
||||
--gradient_checkpointing \
|
||||
--mixed_precision="bf16" \
|
||||
--adam_weight_decay=3e-2 \
|
||||
--adam_epsilon=1e-10 \
|
||||
--vae_mini_batch=1 \
|
||||
--max_grad_norm=0.05 \
|
||||
--enable_bucket \
|
||||
--uniform_sampling \
|
||||
--trainable_modules "."
|
||||
```
|
||||
|
||||
#### 3.6.2 Training Without DeepSpeed or FSDP
|
||||
|
||||
**This approach is not recommended as it lacks VRAM-saving backends and may easily cause out-of-memory errors**. This is provided for reference only.
|
||||
|
||||
```sh
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
# NCCL_IB_DISABLE=1 and NCCL_P2P_DISABLE=1 are used in multi nodes without RDMA.
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --mixed_precision="bf16" scripts/qwenimage21/train.py \
|
||||
--pretrained_model_name_or_path=$MODEL_NAME \
|
||||
--train_data_dir=$DATASET_NAME \
|
||||
--train_data_meta=$DATASET_META_NAME \
|
||||
--train_batch_size=1 \
|
||||
--image_sample_size=1024 \
|
||||
--gradient_accumulation_steps=1 \
|
||||
--dataloader_num_workers=8 \
|
||||
--num_train_epochs=100 \
|
||||
--checkpointing_steps=50 \
|
||||
--learning_rate=2e-05 \
|
||||
--lr_scheduler="constant_with_warmup" \
|
||||
--lr_warmup_steps=100 \
|
||||
--seed=42 \
|
||||
--output_dir="output_dir_qwenimage21" \
|
||||
--gradient_checkpointing \
|
||||
--mixed_precision="bf16" \
|
||||
--adam_weight_decay=3e-2 \
|
||||
--adam_epsilon=1e-10 \
|
||||
--vae_mini_batch=1 \
|
||||
--max_grad_norm=0.05 \
|
||||
--enable_bucket \
|
||||
--uniform_sampling \
|
||||
--trainable_modules "."
|
||||
```
|
||||
|
||||
### 3.7 Multi-Machine Distributed Training
|
||||
|
||||
**Suitable for**: Ultra-large-scale datasets, faster training speed
|
||||
|
||||
#### 3.7.1 Environment Configuration
|
||||
|
||||
Assuming 2 machines with 8 GPUs each:
|
||||
|
||||
**Machine 0 (Master)**:
|
||||
```bash
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
export MASTER_ADDR="192.168.1.100" # Master machine IP
|
||||
export MASTER_PORT=10086
|
||||
export WORLD_SIZE=2 # Total number of machines
|
||||
export NUM_PROCESS=16 # Total processes = machines × 8
|
||||
export RANK=0 # Current machine rank (0 or 1)
|
||||
# NCCL_IB_DISABLE=1 and NCCL_P2P_DISABLE=1 are used in multi nodes without RDMA.
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --mixed_precision="bf16" --main_process_ip=$MASTER_ADDR --main_process_port=$MASTER_PORT --num_machines=$WORLD_SIZE --num_processes=$NUM_PROCESS --machine_rank=$RANK --use_deepspeed --deepspeed_config_file config/zero_stage2_config.json --deepspeed_multinode_launcher standard scripts/qwenimage21/train.py \
|
||||
--pretrained_model_name_or_path=$MODEL_NAME \
|
||||
--train_data_dir=$DATASET_NAME \
|
||||
--train_data_meta=$DATASET_META_NAME \
|
||||
--train_batch_size=1 \
|
||||
--image_sample_size=1024 \
|
||||
--gradient_accumulation_steps=1 \
|
||||
--dataloader_num_workers=8 \
|
||||
--num_train_epochs=100 \
|
||||
--checkpointing_steps=50 \
|
||||
--learning_rate=2e-05 \
|
||||
--lr_scheduler="constant_with_warmup" \
|
||||
--lr_warmup_steps=100 \
|
||||
--seed=42 \
|
||||
--output_dir="output_dir_qwenimage21" \
|
||||
--gradient_checkpointing \
|
||||
--mixed_precision="bf16" \
|
||||
--adam_weight_decay=3e-2 \
|
||||
--adam_epsilon=1e-10 \
|
||||
--vae_mini_batch=1 \
|
||||
--max_grad_norm=0.05 \
|
||||
--enable_bucket \
|
||||
--uniform_sampling \
|
||||
--trainable_modules "."
|
||||
```
|
||||
|
||||
**Machine 1 (Worker)**:
|
||||
```bash
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
export MASTER_ADDR="192.168.1.100" # Same as Master
|
||||
export MASTER_PORT=10086
|
||||
export WORLD_SIZE=2
|
||||
export NUM_PROCESS=16
|
||||
export RANK=1 # Note this is 1
|
||||
# NCCL_IB_DISABLE=1 and NCCL_P2P_DISABLE=1 are used in multi nodes without RDMA.
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
# Use the same accelerate launch command as Machine 0
|
||||
```
|
||||
|
||||
#### 3.7.2 Multi-Machine Training Notes
|
||||
|
||||
- **Network Requirements**:
|
||||
- RDMA/InfiniBand recommended (high performance)
|
||||
- Without RDMA, add environment variables:
|
||||
```bash
|
||||
export NCCL_IB_DISABLE=1
|
||||
export NCCL_P2P_DISABLE=1
|
||||
```
|
||||
|
||||
- **Data Synchronization**: All machines must be able to access the same data paths (NFS/shared storage)
|
||||
|
||||
## 4. Inference Testing
|
||||
|
||||
> ℹ️ **Multi-GPU (Ulysses only)**: Qwen-Image 2.1 supports Ulysses (head-parallel) sequence parallelism — set `ulysses_degree > 1` to split a single image's denoising across GPUs (lower latency and less activation memory per GPU, mathematically identical to single-GPU). `ring_degree` **must stay 1**: ring attention rotates KV chunks and cannot express 2.1's block-causal mask or its prefix KV cache. `ulysses_degree` must divide `num_attention_heads` (32). See [4.3 Multi-GPU Parallel Inference](#43-multi-gpu-parallel-inference). You can also use the VRAM management modes below (offload / FP8) when a single GPU is not enough.
|
||||
|
||||
### 4.1 Inference Parameter Parsing
|
||||
|
||||
**Key Parameter Descriptions** (see `examples/qwenimage21/predict_t2i.py`):
|
||||
|
||||
| Parameter | Description | Example Value |
|
||||
|------|------|-------|
|
||||
| `GPU_memory_mode` | VRAM management mode, see table below for options | `model_full_load` |
|
||||
| `ulysses_degree` | Ulysses (head) parallelism degree. Must divide `num_attention_heads` (32): 1/2/4/8/16/32; `>1` splits one image across GPUs | 1 |
|
||||
| `ring_degree` | Sequence (ring) parallelism degree. **Must stay 1** — ring cannot express the block-causal mask or prefix KV cache | 1 |
|
||||
| `compile_dit` | Compile Transformer for faster inference (effective at fixed resolution) | `False` |
|
||||
| `model_name` | Model path | `models/Diffusion_Transformer/Qwen-Image-2.1` |
|
||||
| `sampler_name` | Sampler type. Qwen-Image 2.1 is flow-matching, only `Flow` is supported | `Flow` |
|
||||
| `transformer_path` | Path to load trained Transformer weights | `None` |
|
||||
| `vae_path` | Path to load trained VAE weights | `None` |
|
||||
| `lora_path` | LoRA weights path | `None` |
|
||||
| `sample_size` | Generated image resolution `[height, width]`, rounded down to a multiple of 32; `None` falls back to the pipeline default square | `[1024, 1024]` |
|
||||
| `use_kv_cache` | Cache text/condition keys-values after the first denoising step to speed up inference | `True` |
|
||||
| `weight_dtype` | Model weight precision, use `torch.float16` for GPUs without bf16 support | `torch.bfloat16` |
|
||||
| `prompts` | Positive prompts describing the generation content | `["a young girl ..."]` |
|
||||
| `negative_prompt` | Negative prompt for content to avoid | `" "` |
|
||||
| `guidance_scale` | Guidance strength (passed to the pipeline as `true_cfg_scale`) | 1.0 |
|
||||
| `seed` | Random seed for reproducible results | 43 |
|
||||
| `num_inference_steps` | Number of inference steps | 40 |
|
||||
| `lora_weight` | LoRA weight strength | 1 |
|
||||
| `save_path` | Path to save generated images | `samples/qwenimage21-t2i` |
|
||||
|
||||
**VRAM Management Mode Description**:
|
||||
|
||||
| Mode | Description | VRAM Usage |
|
||||
|------|------|---------|
|
||||
| `model_full_load` | Load entire model to GPU | Highest |
|
||||
| `model_full_load_and_qfloat8` | Full load + FP8 quantization | High |
|
||||
| `model_cpu_offload` | Offload model to CPU after use | Medium |
|
||||
| `model_cpu_offload_and_qfloat8` | CPU offload + FP8 quantization | Medium-Low |
|
||||
| `model_group_offload` | Layer groups switch between CPU/CUDA | Low |
|
||||
| `sequential_cpu_offload` | Sequential layer offload (slowest) | Lowest |
|
||||
|
||||
### 4.2 Single GPU Inference
|
||||
|
||||
#### Quick Start
|
||||
|
||||
Run the following command for single GPU inference:
|
||||
|
||||
```bash
|
||||
python examples/qwenimage21/predict_t2i.py
|
||||
```
|
||||
|
||||
Edit `examples/qwenimage21/predict_t2i.py` according to your needs. For first-time inference, focus on these parameters. For other parameters, refer to the inference parameter parsing above.
|
||||
|
||||
```python
|
||||
# Choose based on GPU VRAM
|
||||
GPU_memory_mode = "model_full_load"
|
||||
# Based on actual model path
|
||||
model_name = "models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
# Path to trained weights, e.g., "output_dir_qwenimage21/checkpoint-xxx/diffusion_pytorch_model.safetensors"
|
||||
transformer_path = None
|
||||
# Write based on generation content
|
||||
prompts = ["a young girl with flowing long hair, wearing a white halter dress"]
|
||||
# ...
|
||||
```
|
||||
|
||||
### 4.3 Multi-GPU Parallel Inference
|
||||
|
||||
**Suitable for**: high-resolution generation and faster single-image inference. Qwen-Image 2.1 splits the attention **heads** across GPUs (Ulysses sequence parallelism): after an all-to-all each GPU holds the full sequence for a subset of heads, so the block-causal multi-pass prefill and the prefix KV cache run unchanged and the output is **mathematically identical** to single-GPU inference.
|
||||
|
||||
#### Install Parallel Inference Dependencies
|
||||
|
||||
```bash
|
||||
pip install xfuser==0.4.2 yunchang==0.6.2
|
||||
```
|
||||
|
||||
#### Configure Parallel Strategy
|
||||
|
||||
Edit `examples/qwenimage21/predict_t2i.py`:
|
||||
|
||||
```python
|
||||
# ulysses_degree × ring_degree = number of GPUs; ring_degree MUST stay 1 for Qwen-Image 2.1
|
||||
# For example, using 2 GPUs:
|
||||
ulysses_degree = 2 # Head (Ulysses) parallelism
|
||||
ring_degree = 1 # Must be 1
|
||||
```
|
||||
|
||||
**Configuration Principles**:
|
||||
- `ulysses_degree` must evenly divide `num_attention_heads` (32), i.e. one of 1/2/4/8/16/32.
|
||||
- `ring_degree` must stay **1**: ring attention rotates KV chunks and cannot express 2.1's block-causal mask or its prefix KV cache (the script asserts this).
|
||||
- The joint (text + image) sequence is padded internally to a multiple of `ulysses_degree`; padded keys are masked out, so results match single-GPU exactly.
|
||||
- Ulysses replicates the weights on every GPU (it splits activations, not parameters). If VRAM is tight, also set `fsdp_dit = True` to shard the Transformer.
|
||||
|
||||
**Example Configurations**:
|
||||
|
||||
| GPU Count | ulysses_degree | ring_degree | Description |
|
||||
|---------|---------------|-------------|------|
|
||||
| 1 | 1 | 1 | Single GPU |
|
||||
| 2 | 2 | 1 | Head parallelism |
|
||||
| 4 | 4 | 1 | Head parallelism |
|
||||
| 8 | 8 | 1 | Head parallelism |
|
||||
|
||||
#### Run Multi-GPU Inference
|
||||
|
||||
```bash
|
||||
torchrun --nproc-per-node=2 examples/qwenimage21/predict_t2i.py
|
||||
```
|
||||
|
||||
Set `--nproc-per-node` equal to `ulysses_degree`.
|
||||
|
||||
## 5. Additional Resources
|
||||
|
||||
- **Official GitHub**: https://github.com/aigc-apps/VideoX-Fun
|
||||
@@ -0,0 +1,592 @@
|
||||
# Qwen-Image 2.1 全参数训练指南
|
||||
|
||||
本文档提供 Qwen-Image 2.1 Diffusion Transformer 全参数训练的完整流程,包括环境配置、数据准备、分布式训练与推理测试。
|
||||
|
||||
---
|
||||
|
||||
## 目录
|
||||
- [1. 环境配置](#1-环境配置)
|
||||
- [2. 数据准备](#2-数据准备)
|
||||
- [2.1 快速测试数据集](#21-快速测试数据集)
|
||||
- [2.2 数据集结构](#22-数据集结构)
|
||||
- [2.3 metadata.json 格式](#23-metadatajson-格式)
|
||||
- [2.4 相对路径与绝对路径的用法](#24-相对路径与绝对路径的用法)
|
||||
- [3. 全参数训练](#3-全参数训练)
|
||||
- [3.1 下载预训练模型](#31-下载预训练模型)
|
||||
- [3.2 快速开始(DeepSpeed-Zero-2)](#32-快速开始deepspeed-zero-2)
|
||||
- [3.3 常用训练参数](#33-常用训练参数)
|
||||
- [3.4 训练验证](#34-训练验证)
|
||||
- [3.5 使用 FSDP 训练](#35-使用-fsdp-训练)
|
||||
- [3.6 其他后端](#36-其他后端)
|
||||
- [3.7 多机分布式训练](#37-多机分布式训练)
|
||||
- [4. 推理测试](#4-推理测试)
|
||||
- [4.1 推理参数解析](#41-推理参数解析)
|
||||
- [4.2 单卡推理](#42-单卡推理)
|
||||
- [4.3 多卡并行推理](#43-多卡并行推理)
|
||||
- [5. 更多资源](#5-更多资源)
|
||||
|
||||
---
|
||||
|
||||
## 1. 环境配置
|
||||
|
||||
**方式一:使用 requirements.txt**
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
**方式二:手动安装依赖**
|
||||
|
||||
```bash
|
||||
pip install Pillow einops safetensors timm tomesd librosa "torch>=2.1.2" torchdiffeq torchsde decord datasets numpy scikit-image
|
||||
pip install omegaconf SentencePiece imageio[ffmpeg] imageio[pyav] tensorboard beautifulsoup4 ftfy func_timeout onnxruntime
|
||||
pip install "peft>=0.17.0" "accelerate>=0.25.0" "gradio>=3.41.2" "diffusers>=0.30.1" "transformers>=4.46.2"
|
||||
pip install yunchang xfuser modelscope openpyxl
|
||||
pip uninstall opencv-python opencv-contrib-python opencv-python-headless -y
|
||||
pip install opencv-python-headless
|
||||
pip install deepspeed==0.17.0 numpy==1.26.4
|
||||
```
|
||||
|
||||
**方式三:使用 Docker**
|
||||
|
||||
使用 Docker 时,请确保机器上已正确安装 GPU 驱动与 CUDA 环境,然后执行以下命令:
|
||||
|
||||
```
|
||||
# 拉取镜像
|
||||
docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# 进入镜像
|
||||
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## 2. 数据准备
|
||||
|
||||
### 2.1 快速测试数据集
|
||||
|
||||
我们提供了一个包含若干训练样本的测试数据集。
|
||||
|
||||
```bash
|
||||
# 下载官方 demo 数据集
|
||||
modelscope download --dataset PAI/X-Fun-Images-Demo --local_dir ./datasets/X-Fun-Images-Demo
|
||||
```
|
||||
|
||||
### 2.2 数据集结构
|
||||
|
||||
```
|
||||
📦 datasets/
|
||||
├── 📂 my_dataset/
|
||||
│ ├── 📂 train/
|
||||
│ │ ├── 📄 image001.jpg
|
||||
│ │ ├── 📄 image002.png
|
||||
│ │ └── 📄 ...
|
||||
│ └── 📄 metadata.json
|
||||
```
|
||||
|
||||
### 2.3 metadata.json 格式
|
||||
|
||||
**相对路径格式**(示例):
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "train/image001.jpg",
|
||||
"text": "A beautiful sunset over the ocean, golden hour lighting",
|
||||
"width": 1024,
|
||||
"height": 1024
|
||||
},
|
||||
{
|
||||
"file_path": "train/image002.png",
|
||||
"text": "Portrait of a young woman, studio lighting, high quality",
|
||||
"width": 1024,
|
||||
"height": 1024
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
**绝对路径格式**:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "/mnt/data/images/sunset.jpg",
|
||||
"text": "A beautiful sunset over the ocean",
|
||||
"width": 1024,
|
||||
"height": 1024
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
**关键字段说明**:
|
||||
- `file_path`:图像路径(相对或绝对)
|
||||
- `text`:图像描述(英文 prompt)
|
||||
- `width` / `height`:图像尺寸(**建议**提供以便 bucket 训练;若不提供,训练时会自动读取,当数据存放在 OSS 等慢速系统上时可能拖慢训练)
|
||||
- 可使用 `scripts/process_json_add_width_and_height.py` 为缺少这些字段的 JSON 文件补充 width/height,同时支持图像与视频
|
||||
- 用法:`python scripts/process_json_add_width_and_height.py --input_file datasets/X-Fun-Images-Demo/metadata.json --output_file datasets/X-Fun-Images-Demo/metadata_add_width_height.json`
|
||||
|
||||
> 💡 训练图像以 RGB 读入,并在 VAE 编码前自动合成到一层不透明 alpha 通道上,因此你**无需**提供 RGBA 数据。
|
||||
|
||||
### 2.4 相对路径与绝对路径的用法
|
||||
|
||||
**相对路径**:
|
||||
|
||||
如果数据使用相对路径,按如下方式配置训练脚本:
|
||||
|
||||
```bash
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
```
|
||||
|
||||
**绝对路径**:
|
||||
|
||||
如果数据使用绝对路径,按如下方式配置训练脚本:
|
||||
|
||||
```bash
|
||||
export DATASET_NAME=""
|
||||
export DATASET_META_NAME="/mnt/data/metadata_add_width_height.json"
|
||||
```
|
||||
|
||||
> 💡 **建议**:数据集较小且存放在本地时使用相对路径;数据集存放在外部存储(如 NAS、OSS)或需跨多台机器共享时使用绝对路径。
|
||||
|
||||
---
|
||||
|
||||
## 3. 全参数训练
|
||||
|
||||
### 3.1 下载预训练模型
|
||||
|
||||
```bash
|
||||
# 创建模型目录
|
||||
mkdir -p models/Diffusion_Transformer
|
||||
|
||||
# 下载 Qwen-Image 2.1 官方权重
|
||||
modelscope download --model Qwen/Qwen-Image-2.1 --local_dir models/Diffusion_Transformer/Qwen-Image-2.1
|
||||
```
|
||||
|
||||
> 💡 如果 ModelScope id 与上面不同,请改为官方 Qwen-Image-2.1 发布页对应的 id。你也可以将 `--pretrained_model_name_or_path` 指向任意符合 diffusers 布局、且包含 `transformer/`、`vae/`、`text_encoder/`、`processor/`、`scheduler/` 子目录的本地目录。
|
||||
|
||||
### 3.2 快速开始(DeepSpeed-Zero-2)
|
||||
|
||||
如果你已按 **2.1 快速测试数据集** 下载数据、并按 **3.1 下载预训练模型** 下载权重,可直接复制运行下面的快速开始命令。
|
||||
|
||||
训练推荐使用 DeepSpeed-Zero-2 或 FSDP,这里以 DeepSpeed-Zero-2 为例。
|
||||
|
||||
DeepSpeed-Zero-2 与 FSDP 的区别在于是否对模型权重做分片。**如果多卡使用 DeepSpeed-Zero-2 时显存不足**,可切换为 FSDP。
|
||||
|
||||
```bash
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
# NCCL_IB_DISABLE=1 与 NCCL_P2P_DISABLE=1 用于无 RDMA 的多机环境。
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --use_deepspeed --deepspeed_config_file config/zero_stage2_config.json --deepspeed_multinode_launcher standard scripts/qwenimage21/train.py \
|
||||
--pretrained_model_name_or_path=$MODEL_NAME \
|
||||
--train_data_dir=$DATASET_NAME \
|
||||
--train_data_meta=$DATASET_META_NAME \
|
||||
--train_batch_size=1 \
|
||||
--image_sample_size=1024 \
|
||||
--gradient_accumulation_steps=1 \
|
||||
--dataloader_num_workers=8 \
|
||||
--num_train_epochs=100 \
|
||||
--checkpointing_steps=50 \
|
||||
--learning_rate=2e-05 \
|
||||
--lr_scheduler="constant_with_warmup" \
|
||||
--lr_warmup_steps=100 \
|
||||
--seed=42 \
|
||||
--output_dir="output_dir_qwenimage21" \
|
||||
--gradient_checkpointing \
|
||||
--mixed_precision="bf16" \
|
||||
--adam_weight_decay=3e-2 \
|
||||
--adam_epsilon=1e-10 \
|
||||
--vae_mini_batch=1 \
|
||||
--max_grad_norm=0.05 \
|
||||
--enable_bucket \
|
||||
--uniform_sampling \
|
||||
--trainable_modules "."
|
||||
```
|
||||
|
||||
### 3.3 常用训练参数
|
||||
|
||||
**关键参数说明**:
|
||||
|
||||
| 参数 | 说明 | 示例值 |
|
||||
|-----|------|-------|
|
||||
| `--pretrained_model_name_or_path` | 预训练模型路径 | `models/Diffusion_Transformer/Qwen-Image-2.1` |
|
||||
| `--train_data_dir` | 训练数据目录 | `datasets/X-Fun-Images-Demo/` |
|
||||
| `--train_data_meta` | 训练数据元信息文件 | `datasets/X-Fun-Images-Demo/metadata_add_width_height.json` |
|
||||
| `--train_batch_size` | 每个 batch 的样本数 | 1 |
|
||||
| `--image_sample_size` | 最大训练分辨率,自动分桶 | 1024 |
|
||||
| `--gradient_accumulation_steps` | 梯度累积步数(等效更大 batch) | 1 |
|
||||
| `--dataloader_num_workers` | DataLoader 子进程数 | 8 |
|
||||
| `--num_train_epochs` | 训练 epoch 数 | 100 |
|
||||
| `--checkpointing_steps` | 每 N 步保存一次 checkpoint | 50 |
|
||||
| `--learning_rate` | 初始学习率 | 2e-05 |
|
||||
| `--lr_scheduler` | 学习率调度器 | `constant_with_warmup` |
|
||||
| `--lr_warmup_steps` | 学习率 warmup 步数 | 100 |
|
||||
| `--seed` | 随机种子 | 42 |
|
||||
| `--output_dir` | 输出目录 | `output_dir_qwenimage21` |
|
||||
| `--gradient_checkpointing` | 启用激活重计算 | - |
|
||||
| `--mixed_precision` | 混合精度:`fp16/bf16` | `bf16` |
|
||||
| `--adam_weight_decay` | AdamW 权重衰减 | 3e-2 |
|
||||
| `--adam_epsilon` | AdamW epsilon 值 | 1e-10 |
|
||||
| `--vae_mini_batch` | VAE 编码的 mini-batch 大小 | 1 |
|
||||
| `--max_grad_norm` | 梯度裁剪阈值 | 0.05 |
|
||||
| `--enable_bucket` | 启用 bucket 训练:按分辨率分组训练整图,不做中心裁剪 | - |
|
||||
| `--random_hw_adapt` | 将图像自动缩放到 `[512, image_sample_size]` 区间内的随机尺寸 | - |
|
||||
| `--resume_from_checkpoint` | 从 checkpoint 路径恢复训练,使用 `"latest"` 自动选择最新 | None |
|
||||
| `--uniform_sampling` | 均匀时间步采样 | - |
|
||||
| `--trainable_modules` | 可训练模块(`"."` 表示全部模块) | `"."` |
|
||||
| `--tokenizer_max_length` | 送入 Qwen3-VL 文本编码器的最大 prompt token 长度 | 1024 |
|
||||
| `--validation_steps` | 每 N 步执行一次验证 | 100 |
|
||||
| `--validation_epochs` | 每 N 个 epoch 执行一次验证 | 100 |
|
||||
| `--validation_prompts` | 验证时使用的 prompt | `"1girl, black_hair, ..."` |
|
||||
|
||||
|
||||
### 3.4 训练验证
|
||||
|
||||
你可以配置验证参数,在训练过程中周期性生成测试图像,以便监控训练进度与模型质量。
|
||||
|
||||
**验证参数**:
|
||||
|
||||
```bash
|
||||
accelerate launch --use_deepspeed --deepspeed_config_file config/zero_stage2_config.json --deepspeed_multinode_launcher standard scripts/qwenimage21/train.py \
|
||||
# ... (其他训练参数)
|
||||
--validation_steps=100 \
|
||||
--validation_epochs=100 \
|
||||
--validation_prompts="1girl, black_hair, brown_eyes, earrings, freckles, grey_background, jewelry, lips, long_hair, looking_at_viewer, nose, piercing, realistic, red_lips, solo, upper_body"
|
||||
```
|
||||
|
||||
**参数说明**:
|
||||
|
||||
| 参数 | 说明 | 推荐值 |
|
||||
|-----------|-------------|-------------------|
|
||||
| `--validation_steps` | 每 N 步执行一次验证。若数据集较大、想节省验证时间,可设更大的值(如 100 或 500) | 100 |
|
||||
| `--validation_epochs` | 每 N 个 epoch 执行一次验证 | 100 |
|
||||
| `--validation_prompts` | 用于验证生图的 prompt。多个 prompt 用空格分隔的字符串表示 | 空格分隔的 prompt 字符串 |
|
||||
|
||||
**注意**:
|
||||
- 验证图像会保存到 `output_dir` 目录
|
||||
- 设置 `--validation_steps=1` 表示每步都验证,可能拖慢训练,请按需调整
|
||||
- 多 prompt 验证用法:`--validation_prompts "prompt1" "prompt2" "prompt3"`
|
||||
|
||||
|
||||
### 3.5 使用 FSDP 训练
|
||||
|
||||
**如果多卡使用 DeepSpeed-Zero-2 时显存不足**,可切换为 FSDP。注意 Qwen-Image 2.1 需要 wrap 的 transformer 层类名为 `QwenImage21TransformerBlock`。
|
||||
|
||||
```sh
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
# NCCL_IB_DISABLE=1 与 NCCL_P2P_DISABLE=1 用于无 RDMA 的多机环境。
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --mixed_precision="bf16" --use_fsdp --fsdp_auto_wrap_policy TRANSFORMER_BASED_WRAP --fsdp_transformer_layer_cls_to_wrap=QwenImage21TransformerBlock --fsdp_sharding_strategy "FULL_SHARD" --fsdp_state_dict_type=SHARDED_STATE_DICT --fsdp_backward_prefetch "BACKWARD_PRE" --fsdp_cpu_ram_efficient_loading False scripts/qwenimage21/train.py \
|
||||
--pretrained_model_name_or_path=$MODEL_NAME \
|
||||
--train_data_dir=$DATASET_NAME \
|
||||
--train_data_meta=$DATASET_META_NAME \
|
||||
--train_batch_size=1 \
|
||||
--image_sample_size=1024 \
|
||||
--gradient_accumulation_steps=1 \
|
||||
--dataloader_num_workers=8 \
|
||||
--num_train_epochs=100 \
|
||||
--checkpointing_steps=50 \
|
||||
--learning_rate=2e-05 \
|
||||
--lr_scheduler="constant_with_warmup" \
|
||||
--lr_warmup_steps=100 \
|
||||
--seed=42 \
|
||||
--output_dir="output_dir_qwenimage21" \
|
||||
--gradient_checkpointing \
|
||||
--mixed_precision="bf16" \
|
||||
--adam_weight_decay=3e-2 \
|
||||
--adam_epsilon=1e-10 \
|
||||
--vae_mini_batch=1 \
|
||||
--max_grad_norm=0.05 \
|
||||
--enable_bucket \
|
||||
--uniform_sampling \
|
||||
--trainable_modules "."
|
||||
```
|
||||
|
||||
### 3.6 其他后端
|
||||
|
||||
#### 3.6.1 使用 DeepSpeed-Zero-3 训练
|
||||
|
||||
目前不太推荐 DeepSpeed Zero-3。在本仓库中,使用 FSDP 报错更少、更稳定。
|
||||
|
||||
DeepSpeed Zero-3:
|
||||
|
||||
训练结束后,可用以下命令得到最终模型:
|
||||
|
||||
```sh
|
||||
python scripts/zero_to_bf16.py output_dir/checkpoint-{our-num-steps} output_dir/checkpoint-{your-num-steps}-outputs --max_shard_size 80GB --safe_serialization
|
||||
```
|
||||
|
||||
训练 shell 命令:
|
||||
```sh
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
# NCCL_IB_DISABLE=1 与 NCCL_P2P_DISABLE=1 用于无 RDMA 的多机环境。
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --zero_stage 3 --zero3_save_16bit_model true --zero3_init_flag true --use_deepspeed --deepspeed_config_file config/zero_stage3_config.json --deepspeed_multinode_launcher standard scripts/qwenimage21/train.py \
|
||||
--pretrained_model_name_or_path=$MODEL_NAME \
|
||||
--train_data_dir=$DATASET_NAME \
|
||||
--train_data_meta=$DATASET_META_NAME \
|
||||
--train_batch_size=1 \
|
||||
--image_sample_size=1024 \
|
||||
--gradient_accumulation_steps=1 \
|
||||
--dataloader_num_workers=8 \
|
||||
--num_train_epochs=100 \
|
||||
--checkpointing_steps=50 \
|
||||
--learning_rate=2e-05 \
|
||||
--lr_scheduler="constant_with_warmup" \
|
||||
--lr_warmup_steps=100 \
|
||||
--seed=42 \
|
||||
--output_dir="output_dir_qwenimage21" \
|
||||
--gradient_checkpointing \
|
||||
--mixed_precision="bf16" \
|
||||
--adam_weight_decay=3e-2 \
|
||||
--adam_epsilon=1e-10 \
|
||||
--vae_mini_batch=1 \
|
||||
--max_grad_norm=0.05 \
|
||||
--enable_bucket \
|
||||
--uniform_sampling \
|
||||
--trainable_modules "."
|
||||
```
|
||||
|
||||
#### 3.6.2 不使用 DeepSpeed 或 FSDP 训练
|
||||
|
||||
**不推荐该方式,因为缺少省显存的后端,很容易导致显存溢出(OOM)**。此处仅供参考。
|
||||
|
||||
```sh
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
# NCCL_IB_DISABLE=1 与 NCCL_P2P_DISABLE=1 用于无 RDMA 的多机环境。
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --mixed_precision="bf16" scripts/qwenimage21/train.py \
|
||||
--pretrained_model_name_or_path=$MODEL_NAME \
|
||||
--train_data_dir=$DATASET_NAME \
|
||||
--train_data_meta=$DATASET_META_NAME \
|
||||
--train_batch_size=1 \
|
||||
--image_sample_size=1024 \
|
||||
--gradient_accumulation_steps=1 \
|
||||
--dataloader_num_workers=8 \
|
||||
--num_train_epochs=100 \
|
||||
--checkpointing_steps=50 \
|
||||
--learning_rate=2e-05 \
|
||||
--lr_scheduler="constant_with_warmup" \
|
||||
--lr_warmup_steps=100 \
|
||||
--seed=42 \
|
||||
--output_dir="output_dir_qwenimage21" \
|
||||
--gradient_checkpointing \
|
||||
--mixed_precision="bf16" \
|
||||
--adam_weight_decay=3e-2 \
|
||||
--adam_epsilon=1e-10 \
|
||||
--vae_mini_batch=1 \
|
||||
--max_grad_norm=0.05 \
|
||||
--enable_bucket \
|
||||
--uniform_sampling \
|
||||
--trainable_modules "."
|
||||
```
|
||||
|
||||
### 3.7 多机分布式训练
|
||||
|
||||
**适用于**:超大规模数据集、更快的训练速度
|
||||
|
||||
#### 3.7.1 环境配置
|
||||
|
||||
假设有 2 台机器、每台 8 卡:
|
||||
|
||||
**机器 0(Master)**:
|
||||
```bash
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
export MASTER_ADDR="192.168.1.100" # 主机器 IP
|
||||
export MASTER_PORT=10086
|
||||
export WORLD_SIZE=2 # 机器总数
|
||||
export NUM_PROCESS=16 # 总进程数 = 机器数 × 8
|
||||
export RANK=0 # 当前机器 rank(0 或 1)
|
||||
# NCCL_IB_DISABLE=1 与 NCCL_P2P_DISABLE=1 用于无 RDMA 的多机环境。
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --mixed_precision="bf16" --main_process_ip=$MASTER_ADDR --main_process_port=$MASTER_PORT --num_machines=$WORLD_SIZE --num_processes=$NUM_PROCESS --machine_rank=$RANK --use_deepspeed --deepspeed_config_file config/zero_stage2_config.json --deepspeed_multinode_launcher standard scripts/qwenimage21/train.py \
|
||||
--pretrained_model_name_or_path=$MODEL_NAME \
|
||||
--train_data_dir=$DATASET_NAME \
|
||||
--train_data_meta=$DATASET_META_NAME \
|
||||
--train_batch_size=1 \
|
||||
--image_sample_size=1024 \
|
||||
--gradient_accumulation_steps=1 \
|
||||
--dataloader_num_workers=8 \
|
||||
--num_train_epochs=100 \
|
||||
--checkpointing_steps=50 \
|
||||
--learning_rate=2e-05 \
|
||||
--lr_scheduler="constant_with_warmup" \
|
||||
--lr_warmup_steps=100 \
|
||||
--seed=42 \
|
||||
--output_dir="output_dir_qwenimage21" \
|
||||
--gradient_checkpointing \
|
||||
--mixed_precision="bf16" \
|
||||
--adam_weight_decay=3e-2 \
|
||||
--adam_epsilon=1e-10 \
|
||||
--vae_mini_batch=1 \
|
||||
--max_grad_norm=0.05 \
|
||||
--enable_bucket \
|
||||
--uniform_sampling \
|
||||
--trainable_modules "."
|
||||
```
|
||||
|
||||
**机器 1(Worker)**:
|
||||
```bash
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
export MASTER_ADDR="192.168.1.100" # 与 Master 相同
|
||||
export MASTER_PORT=10086
|
||||
export WORLD_SIZE=2
|
||||
export NUM_PROCESS=16
|
||||
export RANK=1 # 注意这里是 1
|
||||
# NCCL_IB_DISABLE=1 与 NCCL_P2P_DISABLE=1 用于无 RDMA 的多机环境。
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
# 使用与机器 0 相同的 accelerate launch 命令
|
||||
```
|
||||
|
||||
#### 3.7.2 多机训练注意事项
|
||||
|
||||
- **网络要求**:
|
||||
- 推荐 RDMA/InfiniBand(高性能)
|
||||
- 无 RDMA 时,添加环境变量:
|
||||
```bash
|
||||
export NCCL_IB_DISABLE=1
|
||||
export NCCL_P2P_DISABLE=1
|
||||
```
|
||||
|
||||
- **数据同步**:所有机器必须能访问相同的数据路径(NFS/共享存储)
|
||||
|
||||
## 4. 推理测试
|
||||
|
||||
> ℹ️ **支持多卡(仅 Ulysses)**:Qwen-Image 2.1 支持 Ulysses(head 并行)序列并行——设 `ulysses_degree > 1` 即可把单张图的去噪切分到多卡(降低单卡延迟与激活显存,且与单卡数学等价)。`ring_degree` **必须保持为 1**:ring attention 会旋转 KV 分块,无法表达 2.1 的 block-causal 掩码与 prefix KV cache。`ulysses_degree` 必须能整除 `num_attention_heads`(32)。详见 [4.3 多卡并行推理](#43-多卡并行推理)。单卡显存不足时,也可使用下方的显存管理模式(offload / FP8)。
|
||||
|
||||
### 4.1 推理参数解析
|
||||
|
||||
**关键参数说明**(见 `examples/qwenimage21/predict_t2i.py`):
|
||||
|
||||
| 参数 | 说明 | 示例值 |
|
||||
|------|------|-------|
|
||||
| `GPU_memory_mode` | 显存管理模式,可选项见下表 | `model_full_load` |
|
||||
| `ulysses_degree` | Ulysses(head)并行度。需整除 `num_attention_heads`(32),即 1/2/4/8/16/32;`>1` 时把单图切分到多卡 | 1 |
|
||||
| `ring_degree` | sequence(ring)并行度。**必须保持为 1**——ring 无法表达 block-causal 掩码与 prefix KV cache | 1 |
|
||||
| `compile_dit` | 编译 Transformer 以加速推理(固定分辨率下有效) | `False` |
|
||||
| `model_name` | 模型路径 | `models/Diffusion_Transformer/Qwen-Image-2.1` |
|
||||
| `sampler_name` | 采样器类型。Qwen-Image 2.1 为 flow-matching,仅支持 `Flow` | `Flow` |
|
||||
| `transformer_path` | 加载已训练 Transformer 权重的路径 | `None` |
|
||||
| `vae_path` | 加载已训练 VAE 权重的路径 | `None` |
|
||||
| `lora_path` | LoRA 权重路径 | `None` |
|
||||
| `sample_size` | 生成图像分辨率 `[height, width]`,会向下取整到 32 的倍数;为 `None` 时回退到 pipeline 默认方图 | `[1024, 1024]` |
|
||||
| `use_kv_cache` | 在第一个去噪步后缓存文本/条件的 key-value 以加速推理 | `True` |
|
||||
| `weight_dtype` | 模型权重精度,不支持 bf16 的 GPU 请用 `torch.float16` | `torch.bfloat16` |
|
||||
| `prompts` | 描述生成内容的正向 prompt | `["a young girl ..."]` |
|
||||
| `negative_prompt` | 需要规避内容的负向 prompt | `" "` |
|
||||
| `guidance_scale` | 引导强度(以 `true_cfg_scale` 传入 pipeline) | 1.0 |
|
||||
| `seed` | 随机种子,用于复现结果 | 43 |
|
||||
| `num_inference_steps` | 推理步数 | 40 |
|
||||
| `lora_weight` | LoRA 权重强度 | 1 |
|
||||
| `save_path` | 生成图像保存路径 | `samples/qwenimage21-t2i` |
|
||||
|
||||
**显存管理模式说明**:
|
||||
|
||||
| 模式 | 说明 | 显存占用 |
|
||||
|------|------|---------|
|
||||
| `model_full_load` | 将整个模型加载到 GPU | 最高 |
|
||||
| `model_full_load_and_qfloat8` | 全量加载 + FP8 量化 | 高 |
|
||||
| `model_cpu_offload` | 用完后将模型 offload 到 CPU | 中 |
|
||||
| `model_cpu_offload_and_qfloat8` | CPU offload + FP8 量化 | 中低 |
|
||||
| `model_group_offload` | 以层组为单位在 CPU/CUDA 间切换 | 低 |
|
||||
| `sequential_cpu_offload` | 逐层 offload(最慢) | 最低 |
|
||||
|
||||
### 4.2 单卡推理
|
||||
|
||||
#### 快速开始
|
||||
|
||||
运行以下命令进行单卡推理:
|
||||
|
||||
```bash
|
||||
python examples/qwenimage21/predict_t2i.py
|
||||
```
|
||||
|
||||
按需编辑 `examples/qwenimage21/predict_t2i.py`。首次推理重点关注以下参数,其余参数参见上面的推理参数解析。
|
||||
|
||||
```python
|
||||
# 根据 GPU 显存选择
|
||||
GPU_memory_mode = "model_full_load"
|
||||
# 根据实际模型路径填写
|
||||
model_name = "models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
# 已训练权重路径,例如 "output_dir_qwenimage21/checkpoint-xxx/diffusion_pytorch_model.safetensors"
|
||||
transformer_path = None
|
||||
# 根据生成内容填写
|
||||
prompts = ["a young girl with flowing long hair, wearing a white halter dress"]
|
||||
# ...
|
||||
```
|
||||
|
||||
### 4.3 多卡并行推理
|
||||
|
||||
**适合场景**:高分辨率生成、加速单图推理。Qwen-Image 2.1 按注意力 **head** 切分到多卡(Ulysses 序列并行):经过 all-to-all 后每张卡持有"完整序列 + 部分 head",因此 block-causal 多趟 prefill 与 prefix KV cache 逻辑原样运行,输出与单卡**数学等价**。
|
||||
|
||||
#### 安装并行推理依赖
|
||||
|
||||
```bash
|
||||
pip install xfuser==0.4.2 yunchang==0.6.2
|
||||
```
|
||||
|
||||
#### 配置并行策略
|
||||
|
||||
编辑 `examples/qwenimage21/predict_t2i.py`:
|
||||
|
||||
```python
|
||||
# ulysses_degree × ring_degree = GPU 数量;Qwen-Image 2.1 的 ring_degree 必须保持为 1
|
||||
# 例如使用 2 张 GPU:
|
||||
ulysses_degree = 2 # Head(Ulysses)并行
|
||||
ring_degree = 1 # 必须为 1
|
||||
```
|
||||
|
||||
**配置原则**:
|
||||
- `ulysses_degree` 必须能整除 `num_attention_heads`(32),即取 1/2/4/8/16/32 之一。
|
||||
- `ring_degree` 必须保持为 **1**:ring attention 会旋转 KV 分块,无法表达 2.1 的 block-causal 掩码与 prefix KV cache(脚本内已加断言)。
|
||||
- joint(文本 + 图像)序列会在内部 pad 到 `ulysses_degree` 的倍数,pad 位置的 key 会被置为 invalid,因此结果与单卡完全一致。
|
||||
- Ulysses 在每张卡上都复制模型权重(切分的是激活而非参数)。显存吃紧时可同时设 `fsdp_dit = True` 对 Transformer 做权重分片。
|
||||
|
||||
**示例配置**:
|
||||
|
||||
| GPU 数量 | ulysses_degree | ring_degree | 说明 |
|
||||
|---------|---------------|-------------|------|
|
||||
| 1 | 1 | 1 | 单卡 |
|
||||
| 2 | 2 | 1 | Head 并行 |
|
||||
| 4 | 4 | 1 | Head 并行 |
|
||||
| 8 | 8 | 1 | Head 并行 |
|
||||
|
||||
#### 运行多卡推理
|
||||
|
||||
```bash
|
||||
torchrun --nproc-per-node=2 examples/qwenimage21/predict_t2i.py
|
||||
```
|
||||
|
||||
将 `--nproc-per-node` 设为与 `ulysses_degree` 相同。
|
||||
|
||||
## 5. 更多资源
|
||||
|
||||
- **官方 GitHub**: https://github.com/aigc-apps/VideoX-Fun
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,32 @@
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Qwen-Image-2.1"
|
||||
export DATASET_NAME="datasets/X-Fun-Images-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Images-Demo/metadata_add_width_height.json"
|
||||
# NCCL_IB_DISABLE=1 and NCCL_P2P_DISABLE=1 are used in multi nodes without RDMA.
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --use_deepspeed --deepspeed_config_file config/zero_stage2_config.json --deepspeed_multinode_launcher standard scripts/qwenimage21/train.py \
|
||||
--pretrained_model_name_or_path=$MODEL_NAME \
|
||||
--train_data_dir=$DATASET_NAME \
|
||||
--train_data_meta=$DATASET_META_NAME \
|
||||
--train_batch_size=1 \
|
||||
--image_sample_size=1024 \
|
||||
--gradient_accumulation_steps=1 \
|
||||
--dataloader_num_workers=8 \
|
||||
--num_train_epochs=100 \
|
||||
--checkpointing_steps=50 \
|
||||
--learning_rate=2e-05 \
|
||||
--lr_scheduler="constant_with_warmup" \
|
||||
--lr_warmup_steps=100 \
|
||||
--seed=42 \
|
||||
--output_dir="output_dir_qwenimage21" \
|
||||
--gradient_checkpointing \
|
||||
--mixed_precision="bf16" \
|
||||
--adam_weight_decay=3e-2 \
|
||||
--adam_epsilon=1e-10 \
|
||||
--vae_mini_batch=1 \
|
||||
--max_grad_norm=0.05 \
|
||||
--enable_bucket \
|
||||
--uniform_sampling \
|
||||
--trainable_modules "."
|
||||
@@ -49,7 +49,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
import datasets
|
||||
@@ -70,6 +69,8 @@ from videox_fun.models import (AutoencoderKLQwenImage,
|
||||
QwenImageControlTransformer2DModel)
|
||||
from videox_fun.pipeline import QwenImageControlPipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
@@ -842,15 +843,21 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = QwenImageControlTransformer2DModel.from_pretrained(
|
||||
ema_module = QwenImageControlTransformer2DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path,
|
||||
subfolder="transformer",
|
||||
torch_dtype=weight_dtype,
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=QwenImageControlTransformer2DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=QwenImageControlTransformer2DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -867,8 +874,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -895,6 +907,7 @@ def main():
|
||||
_, ema_kwargs = QwenImageControlTransformer2DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = QwenImageControlTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=QwenImageControlTransformer2DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -909,7 +922,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = QwenImageControlTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1337,7 +1351,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1645,27 +1659,37 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1674,23 +1698,29 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -47,7 +47,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
import datasets
|
||||
@@ -69,6 +68,7 @@ from videox_fun.models import (AutoencoderKLQwenImage,
|
||||
QwenImageTransformer2DModel)
|
||||
from videox_fun.pipeline import QwenImageControlNetPipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
@@ -900,7 +900,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = QwenImageTransformer2DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1376,7 +1377,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1651,21 +1652,31 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
cn_transformer,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
cn_transformer,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1674,18 +1685,23 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
tokenizer_2,
|
||||
transformer3d,
|
||||
cn_transformer,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
cn_transformer,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -0,0 +1,374 @@
|
||||
# TAE (Tiny AutoEncoder) Training Guide
|
||||
|
||||
This document provides a complete workflow for training / fine-tuning the TAE (Tiny AutoEncoder, `AutoencoderTinyWan`) against the full Wan VAE, including environment setup, data preparation, training, and using the trained checkpoint for inference.
|
||||
|
||||
> **Note**: The TAE ([madebyollin/taehv](https://github.com/madebyollin/taehv)) is a ~20MB distilled VAE that shares the **exact latent space** of the full-size Wan VAEs. It decodes ~100x faster than the full VAE at slightly lower reconstruction quality, and is mainly used as a fast preview / low-memory decoder during diffusion sampling. Training is a plain reconstruction distillation:
|
||||
>
|
||||
> ```
|
||||
> x (video, [-1, 1])
|
||||
> -> teacher (full VAE, frozen) : z_full = teacher.encode(x).mode()
|
||||
> -> TAE encoder : z_tae = tae.encode(x).mode()
|
||||
> -> TAE decoder : x_hat = tae.decode(z_tae).sample
|
||||
> loss = pixel L1(x_hat, x) + latent_loss_weight * MSE(z_tae, z_full)
|
||||
> ```
|
||||
>
|
||||
> The latent MSE anchors the TAE latents to the native VAE latent space, which is what keeps TAE latents interchangeable with the diffusion model latents.
|
||||
|
||||
Two TAE families are supported (selected via `--config_path`, which determines the teacher VAE):
|
||||
|
||||
| Family | Latent | Teacher full VAE | `--config_path` | Models |
|
||||
|--------|--------|------------------|-----------------|--------|
|
||||
| taew2_1 | 16ch, patch_size=1 | `AutoencoderKLWan` (Wan2.1_VAE.pth) | `config/wan2.1/wan_civitai.yaml` | Wan2.1, Wan2.2 14B |
|
||||
| taew2_2 | 48ch, patch_size=2 | `AutoencoderKLWan3_8` (Wan2.2_VAE.pth) | `config/wan2.2/wan_civitai_5b.yaml` | Wan2.2 TI2V-5B / Fun-2.2VAE |
|
||||
|
||||
---
|
||||
|
||||
## Table of Contents
|
||||
- [1. Environment Setup](#1-environment-setup)
|
||||
- [2. Data Preparation](#2-data-preparation)
|
||||
- [2.1 Quick Test Dataset](#21-quick-test-dataset)
|
||||
- [2.2 Dataset Structure](#22-dataset-structure)
|
||||
- [2.3 metadata.json Format](#23-metadatajson-format)
|
||||
- [2.4 Relative vs Absolute Path Usage](#24-relative-vs-absolute-path-usage)
|
||||
- [3. TAE Training](#3-tae-training)
|
||||
- [3.1 Download Pretrained Model](#31-download-pretrained-model)
|
||||
- [3.2 Quick Start](#32-quick-start)
|
||||
- [3.3 Training Parameter Reference](#33-training-parameter-reference)
|
||||
- [3.4 Training Validation](#34-training-validation)
|
||||
- [3.5 Training Tips](#35-training-tips)
|
||||
- [3.6 Multi-Node Distributed Training](#36-multi-node-distributed-training)
|
||||
- [4. Inference Testing](#4-inference-testing)
|
||||
- [4.1 Checkpoint Layout](#41-checkpoint-layout)
|
||||
- [4.2 Use the Trained TAE in Predict Scripts](#42-use-the-trained-tae-in-predict-scripts)
|
||||
- [5. Additional Resources](#5-additional-resources)
|
||||
|
||||
---
|
||||
|
||||
## 1. Environment Setup
|
||||
|
||||
**Option 1: Using requirements.txt**
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
**Option 2: Manual Installation**
|
||||
|
||||
```bash
|
||||
pip install Pillow einops safetensors timm tomesd librosa "torch>=2.1.2" torchdiffeq torchsde decord datasets numpy scikit-image
|
||||
pip install omegaconf SentencePiece imageio[ffmpeg] imageio[pyav] tensorboard beautifulsoup4 ftfy func_timeout onnxruntime
|
||||
pip install "peft>=0.17.0" "accelerate>=0.25.0" "gradio>=3.41.2" "diffusers>=0.30.1" "transformers>=4.46.2"
|
||||
```
|
||||
|
||||
> The TAE itself only has ~20MB of weights, so **plain data parallelism is enough** — DeepSpeed / FSDP is not required (but still supported by the script). The only large model in memory is the frozen teacher full VAE (~1.5GB for the 2.2 VAE); use `--low_vram` if it does not fit together with the training activations.
|
||||
|
||||
---
|
||||
|
||||
## 2. Data Preparation
|
||||
|
||||
### 2.1 Quick Test Dataset
|
||||
|
||||
We provide a test dataset containing several training samples.
|
||||
|
||||
```bash
|
||||
# Download official demo dataset
|
||||
modelscope download --dataset PAI/X-Fun-Videos-Demo --local_dir ./datasets/X-Fun-Videos-Demo
|
||||
```
|
||||
|
||||
### 2.2 Dataset Structure
|
||||
|
||||
```
|
||||
📦 datasets/
|
||||
├── 📂 my_dataset/
|
||||
│ ├── 📂 train/
|
||||
│ │ ├── 📄 video001.mp4
|
||||
│ │ ├── 📄 video002.mp4
|
||||
│ │ └── 📄 ...
|
||||
│ └── 📄 metadata.json
|
||||
```
|
||||
|
||||
### 2.3 metadata.json Format
|
||||
|
||||
**Relative Path Format** (example format):
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "train/video001.mp4",
|
||||
"text": "A beautiful sunset over the ocean, golden hour lighting",
|
||||
"type": "video",
|
||||
"width": 1024,
|
||||
"height": 1024
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
**Absolute Path Format**:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "/mnt/data/videos/sunset.mp4",
|
||||
"text": "A beautiful sunset over the ocean",
|
||||
"type": "video",
|
||||
"width": 1024,
|
||||
"height": 1024
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
**Key Field Descriptions**:
|
||||
- `file_path`: Video path (relative or absolute path)
|
||||
- `text`: Video description (not used by the TAE loss, kept for meta format compatibility)
|
||||
- `type`: Data type, should be `"video"`
|
||||
- `width` / `height`: Video width and height (**recommended to provide**, used for bucket training).
|
||||
- You can use `scripts/process_json_add_width_and_height.py` to extract width and height from JSON files without these fields.
|
||||
|
||||
### 2.4 Relative vs Absolute Path Usage
|
||||
|
||||
**Relative Path**:
|
||||
|
||||
```bash
|
||||
export DATASET_NAME="datasets/X-Fun-Videos-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Videos-Demo/metadata.json"
|
||||
```
|
||||
|
||||
**Absolute Path**:
|
||||
|
||||
```bash
|
||||
export DATASET_NAME=""
|
||||
export DATASET_META_NAME="/mnt/data/metadata.json"
|
||||
```
|
||||
|
||||
> 💡 **Recommendation**: If the dataset is small and stored locally, use relative paths. If the dataset is stored on external storage (e.g., NAS, OSS) or shared across multiple machines, use absolute paths.
|
||||
|
||||
---
|
||||
|
||||
## 3. TAE Training
|
||||
|
||||
### 3.1 Download Pretrained Model
|
||||
|
||||
The training script only needs the **full VAE weights** (used as the frozen teacher), which ship inside the model directory:
|
||||
|
||||
```bash
|
||||
mkdir -p models/Diffusion_Transformer
|
||||
|
||||
# taew2_2 family (Wan2.2 TI2V-5B, 48ch latent, contains Wan2.2_VAE.pth)
|
||||
modelscope download --model Wan-AI/Wan2.2-TI2V-5B --local_dir models/Diffusion_Transformer/Wan2.2-TI2V-5B
|
||||
|
||||
# taew2_1 family (Wan2.1, 16ch latent, contains Wan2.1_VAE.pth)
|
||||
# modelscope download --model Wan-AI/Wan2.1-T2V-14B --local_dir models/Diffusion_Transformer/Wan2.1-T2V-14B
|
||||
```
|
||||
|
||||
Optionally download the released TAE weights to warm-start instead of training from scratch:
|
||||
|
||||
```bash
|
||||
# from https://github.com/madebyollin/taehv
|
||||
wget https://github.com/madebyollin/taehv/raw/main/taew2_2.safetensors
|
||||
# wget https://github.com/madebyollin/taehv/raw/main/taew2_1.safetensors
|
||||
```
|
||||
|
||||
### 3.2 Quick Start
|
||||
|
||||
**Wan2.2 TI2V-5B / Fun-2.2VAE (taew2_2) Example**:
|
||||
|
||||
```bash
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Wan2.2-TI2V-5B"
|
||||
export DATASET_NAME="datasets/X-Fun-Videos-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Videos-Demo/metadata.json"
|
||||
# Optional: warm-start from released TAE weights instead of training from scratch.
|
||||
export TAE_PATH="models/Diffusion_Transformer/taew2_2.safetensors"
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --mixed_precision="bf16" scripts/taehv/train_taehv.py \
|
||||
--config_path="config/wan2.2/wan_civitai_5b.yaml" \
|
||||
--pretrained_model_name_or_path=$MODEL_NAME \
|
||||
--tae_path=$TAE_PATH \
|
||||
--train_data_dir=$DATASET_NAME \
|
||||
--train_data_meta=$DATASET_META_NAME \
|
||||
--video_sample_size=512 \
|
||||
--video_sample_stride=1 \
|
||||
--video_sample_n_frames=33 \
|
||||
--train_batch_size=1 \
|
||||
--gradient_accumulation_steps=1 \
|
||||
--dataloader_num_workers=4 \
|
||||
--num_train_epochs=100 \
|
||||
--checkpointing_steps=500 \
|
||||
--learning_rate=1e-04 \
|
||||
--lr_scheduler="constant_with_warmup" \
|
||||
--lr_warmup_steps=100 \
|
||||
--latent_loss_weight=1.0 \
|
||||
--seed=42 \
|
||||
--output_dir="output_dir_taehv_w2.2" \
|
||||
--mixed_precision="bf16" \
|
||||
--adam_weight_decay=1e-2 \
|
||||
--adam_epsilon=1e-08 \
|
||||
--vae_mini_batch=1 \
|
||||
--max_grad_norm=1.0 \
|
||||
--random_hw_adapt \
|
||||
--enable_bucket \
|
||||
--trainable_modules "." \
|
||||
--resume_from_checkpoint=latest
|
||||
```
|
||||
|
||||
**Wan2.1 / Wan2.2 14B (taew2_1) Example**:
|
||||
|
||||
Same as above, with these changes:
|
||||
|
||||
```bash
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Wan2.1-T2V-14B"
|
||||
export TAE_PATH="taew2_1.safetensors"
|
||||
# ...
|
||||
--config_path="config/wan2.1/wan_civitai.yaml" \
|
||||
--output_dir="output_dir_taehv_w2.1" \
|
||||
# ...
|
||||
```
|
||||
|
||||
### 3.3 Training Parameter Reference
|
||||
|
||||
**Key Parameter Descriptions**:
|
||||
|
||||
| Parameter | Description | Example Value |
|
||||
|-----------|-------------|---------------|
|
||||
| `--config_path` | Model config yaml; its `vae_kwargs.vae_type` selects the teacher full VAE family | `config/wan2.2/wan_civitai_5b.yaml` |
|
||||
| `--pretrained_model_name_or_path` | Model directory containing the full VAE weights | `models/Diffusion_Transformer/Wan2.2-TI2V-5B` |
|
||||
| `--tae_path` | Optional TAE weights to warm-start from (file / directory). Omit to train from scratch | `taew2_2.safetensors` |
|
||||
| `--tae_arch_variant` | TAE decoder variant when training from scratch: base (`None`) or `super` (~2x decoder params) | `None` |
|
||||
| `--vae_path` | Optional hot-load path for other full VAE weights (teacher) | `None` |
|
||||
| `--freeze_tae_encoder` | Train the TAE decoder only (decoder-only distillation) | - |
|
||||
| `--use_taehv_sequential` | Run the TAE in O(1)-memory sequential mode instead of parallel | - |
|
||||
| `--latent_loss_weight` | Weight of the latent MSE (TAE latent vs. full VAE latent) relative to pixel L1 | 1.0 |
|
||||
| `--train_data_dir` | Training data directory | `datasets/X-Fun-Videos-Demo/` |
|
||||
| `--train_data_meta` | Training data metadata file | `datasets/X-Fun-Videos-Demo/metadata.json` |
|
||||
| `--train_batch_size` | Batch size (per device) | 1 |
|
||||
| `--video_sample_size` | Training resolution | 512 |
|
||||
| `--video_sample_stride` | Video sample stride | 1 |
|
||||
| `--video_sample_n_frames` | Number of frames to sample. **Must be 4k+1** (33, 49, 81, ...) | 33 |
|
||||
| `--vae_mini_batch` | Mini batch size for teacher VAE encoding | 1 |
|
||||
| `--gradient_accumulation_steps` | Gradient accumulation steps | 1 |
|
||||
| `--dataloader_num_workers` | Number of DataLoader workers | 4 |
|
||||
| `--num_train_epochs` | Number of training epochs | 100 |
|
||||
| `--checkpointing_steps` | Save a checkpoint every N steps | 500 |
|
||||
| `--checkpoints_total_limit` | Max number of checkpoints to store | `None` |
|
||||
| `--learning_rate` | Initial learning rate | 1e-4 |
|
||||
| `--lr_scheduler` | Learning rate scheduler | `constant_with_warmup` |
|
||||
| `--lr_warmup_steps` | Learning rate warmup steps | 100 |
|
||||
| `--use_8bit_adam` / `--use_came` | Alternative optimizers | - |
|
||||
| `--use_ema` | Keep an EMA copy of the TAE (used for validation and final save) | - |
|
||||
| `--seed` | Random seed | 42 |
|
||||
| `--output_dir` | Output directory | `output_dir_taehv_w2.2` |
|
||||
| `--mixed_precision` | Mixed precision: `fp16/bf16` | `bf16` |
|
||||
| `--max_grad_norm` | Maximum gradient norm for clipping | 1.0 |
|
||||
| `--enable_bucket` | Enable bucket training without cropping, groups by resolution | - |
|
||||
| `--random_hw_adapt` | Randomly scale videos to a range of resolutions | - |
|
||||
| `--low_vram` | Keep the teacher VAE on CPU and move it to GPU only when encoding | - |
|
||||
| `--trainable_modules` | Trainable modules (`"."` means all modules) | `"."` |
|
||||
| `--trainable_modules_low_learning_rate` | Trainable modules with lr/2 | `[]` |
|
||||
| `--resume_from_checkpoint` | Resume training from checkpoint, use `"latest"` to auto-select | `latest` |
|
||||
| `--validation_steps` / `--validation_epochs` | Run validation every N steps / epochs | 2000 / 5 |
|
||||
| `--validation_paths` | Video paths for validation reconstruction comparison | `"asset/1.mp4"` |
|
||||
|
||||
**Sample Size Configuration Guide**:
|
||||
- `video_sample_size` represents the training resolution; when `random_hw_adapt` is enabled, it represents the minimum resolution.
|
||||
- `video_sample_n_frames` must satisfy `4k+1` (e.g. 33, 49, 81) because both the full VAE and the TAE are causal 4x temporal compressors.
|
||||
|
||||
### 3.4 Training Validation
|
||||
|
||||
You can configure validation parameters to periodically reconstruct test videos with both the TAE and the full VAE during training, so you can visually monitor reconstruction quality.
|
||||
|
||||
| Parameter | Description | Recommended Value |
|
||||
|-----------|-------------|-------------------|
|
||||
| `--validation_steps` | Run validation every N steps | 2000 |
|
||||
| `--validation_epochs` | Run validation every N epochs | 5 |
|
||||
| `--validation_paths` | Validation video paths | `"asset/1.mp4"` |
|
||||
|
||||
```bash
|
||||
--validation_paths "asset/1.mp4" \
|
||||
--validation_steps=2000 \
|
||||
--validation_epochs=5
|
||||
```
|
||||
|
||||
**Notes**:
|
||||
- Validation saves three videos per sample into `output_dir/sample/`: `*_input.mp4` (resized input), `*_taehv.mp4` (TAE reconstruction), `*_fullvae.mp4` (full VAE reconstruction for reference).
|
||||
- When `--use_ema` is enabled, validation runs with the EMA weights.
|
||||
|
||||
### 3.5 Training Tips
|
||||
|
||||
- **Warm-start vs. from scratch**: The released TAE weights are already well distilled; fine-tuning from `taew2_x.safetensors` with a small lr (1e-5) is usually enough for domain adaptation. Training from scratch converges but requires much more data/steps.
|
||||
- **Loss balance**: `latent_loss_weight=1.0` keeps the TAE latent aligned with the diffusion latent space. Set it to `0.0` for pure pixel reconstruction (not recommended if you use the TAE latents in the sampling loop).
|
||||
- **Decoder-only distillation**: Add `--freeze_tae_encoder` to only improve decoding quality.
|
||||
- **Memory**: The teacher full VAE is the main memory consumer. Use `--low_vram` to keep it on CPU between encoding steps, or reduce `--video_sample_n_frames` / `--video_sample_size`.
|
||||
- **Sequential TAE**: `--use_taehv_sequential` trades speed for O(1) activation memory w.r.t. video length.
|
||||
- **EMA**: `--use_ema` is recommended for the final deliverable; the final saved `taehv` directory contains the EMA weights.
|
||||
|
||||
### 3.6 Multi-Node Distributed Training
|
||||
|
||||
**Suitable for**: Large-scale datasets, faster training speed
|
||||
|
||||
Assuming 2 machines with 8 GPUs each:
|
||||
|
||||
**Machine 0 (Master)**:
|
||||
```bash
|
||||
export MASTER_ADDR="192.168.1.100" # Master machine IP
|
||||
export MASTER_PORT=10086
|
||||
export WORLD_SIZE=2 # Total number of machines
|
||||
export NUM_PROCESS=16 # Total processes = machines × 8
|
||||
export RANK=0 # Current machine rank (0 or 1)
|
||||
# Without RDMA:
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --mixed_precision="bf16" --main_process_ip=$MASTER_ADDR --main_process_port=$MASTER_PORT --num_machines=$WORLD_SIZE --num_processes=$NUM_PROCESS --machine_rank=$RANK scripts/taehv/train_taehv.py \
|
||||
<same training arguments as the Quick Start>
|
||||
```
|
||||
|
||||
**Machine 1 (Worker)**: use the same command with `export RANK=1`.
|
||||
|
||||
**Notes**:
|
||||
- Without RDMA, add `NCCL_IB_DISABLE=1` and `NCCL_P2P_DISABLE=1`.
|
||||
- All machines must have access to the same data / model paths (NFS/shared storage).
|
||||
|
||||
---
|
||||
|
||||
## 4. Inference Testing
|
||||
|
||||
### 4.1 Checkpoint Layout
|
||||
|
||||
Each checkpoint is written as `output_dir/checkpoint-{step}/`, containing:
|
||||
|
||||
```
|
||||
📦 output_dir_taehv_w2.2/
|
||||
├── 📂 checkpoint-500/
|
||||
│ ├── 📂 taehv/ # TAE weights + config.json (save_pretrained format)
|
||||
│ ├── 📂 taehv_ema/ # only when --use_ema
|
||||
│ └── 📄 sampler_pos_start.pkl
|
||||
├── 📂 sample/ # validation videos
|
||||
└── 📂 logs/ # tensorboard
|
||||
```
|
||||
|
||||
The `taehv` subdirectory is a standard diffusers directory checkpoint and can be loaded directly by `AutoencoderTinyWan.from_pretrained`.
|
||||
|
||||
### 4.2 Use the Trained TAE in Predict Scripts
|
||||
|
||||
Point `tae_path` of any TAE predict script to the `taehv` subdirectory of your checkpoint:
|
||||
|
||||
| Script | Family |
|
||||
|--------|--------|
|
||||
| `examples/wan2.2/predict_ti2v_tae.py` | taew2_2 |
|
||||
| `examples/wan2.2_fun/predict_t2v_2.2vae_tae.py` | taew2_2 |
|
||||
| `examples/wan2.2_fun/predict_i2v_2.2vae_tae.py` | taew2_2 |
|
||||
| `examples/wan2.1/predict_t2v_tae.py` | taew2_1 |
|
||||
| `examples/wan2.1/predict_i2v_tae.py` | taew2_1 |
|
||||
|
||||
```python
|
||||
# e.g. in examples/wan2.2_fun/predict_t2v_2.2vae_tae.py
|
||||
tae_path = "output_dir_taehv_w2.2/checkpoint-500/taehv"
|
||||
```
|
||||
|
||||
The trained TAE is interchangeable with the released one: it keeps the same latent space as the full VAE, so it can be used for fast preview decoding in the diffusion pipeline exactly like `taew2_2.safetensors`.
|
||||
|
||||
---
|
||||
|
||||
## 5. Additional Resources
|
||||
|
||||
- **TAE reference implementation**: https://github.com/madebyollin/taehv
|
||||
- **Official GitHub**: https://github.com/aigc-apps/VideoX-Fun
|
||||
@@ -0,0 +1,374 @@
|
||||
# TAE(Tiny AutoEncoder)训练指南
|
||||
|
||||
本文档提供 TAE(Tiny AutoEncoder,`AutoencoderTinyWan`)针对完整 Wan VAE 进行蒸馏训练/微调的完整流程,包括环境配置、数据准备、训练,以及将训练好的 checkpoint 用于推理。
|
||||
|
||||
> **说明**:TAE([madebyollin/taehv](https://github.com/madebyollin/taehv))是一个约 20MB 的蒸馏 VAE,与完整尺寸的 Wan VAE **共享完全相同的 latent 空间**。它的解码速度比完整 VAE 快约 100 倍,重建质量略有下降,主要用于扩散采样过程中的快速预览/低显存解码。训练采用简单的重建蒸馏范式:
|
||||
>
|
||||
> ```
|
||||
> x (video, [-1, 1])
|
||||
> -> teacher (完整 VAE, 冻结) : z_full = teacher.encode(x).mode()
|
||||
> -> TAE encoder : z_tae = tae.encode(x).mode()
|
||||
> -> TAE decoder : x_hat = tae.decode(z_tae).sample
|
||||
> loss = pixel L1(x_hat, x) + latent_loss_weight * MSE(z_tae, z_full)
|
||||
> ```
|
||||
>
|
||||
> latent MSE 将 TAE 的 latent 锚定到原生 VAE 的 latent 空间,这正是 TAE latent 能与扩散模型 latent 互换的关键。
|
||||
|
||||
支持两个 TAE 家族(通过 `--config_path` 选择,它决定了 teacher VAE):
|
||||
|
||||
| 家族 | Latent | Teacher 完整 VAE | `--config_path` | 适用模型 |
|
||||
|------|--------|------------------|-----------------|----------|
|
||||
| taew2_1 | 16ch, patch_size=1 | `AutoencoderKLWan`(Wan2.1_VAE.pth) | `config/wan2.1/wan_civitai.yaml` | Wan2.1、Wan2.2 14B |
|
||||
| taew2_2 | 48ch, patch_size=2 | `AutoencoderKLWan3_8`(Wan2.2_VAE.pth) | `config/wan2.2/wan_civitai_5b.yaml` | Wan2.2 TI2V-5B / Fun-2.2VAE |
|
||||
|
||||
---
|
||||
|
||||
## 目录
|
||||
- [一、环境配置](#一环境配置)
|
||||
- [二、数据准备](#二数据准备)
|
||||
- [2.1 快速测试数据集](#21-快速测试数据集)
|
||||
- [2.2 数据集结构](#22-数据集结构)
|
||||
- [2.3 metadata.json 格式](#23-metadatajson-格式)
|
||||
- [2.4 相对路径与绝对路径使用方案](#24-相对路径与绝对路径使用方案)
|
||||
- [三、TAE 训练](#三tae-训练)
|
||||
- [3.1 下载预训练模型](#31-下载预训练模型)
|
||||
- [3.2 快速开始](#32-快速开始)
|
||||
- [3.3 训练常用参数解析](#33-训练常用参数解析)
|
||||
- [3.4 训练验证](#34-训练验证)
|
||||
- [3.5 训练技巧](#35-训练技巧)
|
||||
- [3.6 多机分布式训练](#36-多机分布式训练)
|
||||
- [四、推理测试](#四推理测试)
|
||||
- [4.1 Checkpoint 目录结构](#41-checkpoint-目录结构)
|
||||
- [4.2 在 Predict 脚本中使用训练好的 TAE](#42-在-predict-脚本中使用训练好的-tae)
|
||||
- [五、更多资源](#五更多资源)
|
||||
|
||||
---
|
||||
|
||||
## 一、环境配置
|
||||
|
||||
**方式 1:使用 requirements.txt**
|
||||
|
||||
```bash
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
**方式 2:手动安装依赖**
|
||||
|
||||
```bash
|
||||
pip install Pillow einops safetensors timm tomesd librosa "torch>=2.1.2" torchdiffeq torchsde decord datasets numpy scikit-image
|
||||
pip install omegaconf SentencePiece imageio[ffmpeg] imageio[pyav] tensorboard beautifulsoup4 ftfy func_timeout onnxruntime
|
||||
pip install "peft>=0.17.0" "accelerate>=0.25.0" "gradio>=3.41.2" "diffusers>=0.30.1" "transformers>=4.46.2"
|
||||
```
|
||||
|
||||
> TAE 本身只有约 20MB 权重,因此**普通数据并行即可**——不需要 DeepSpeed / FSDP(但脚本仍然支持)。显存中唯一的大模型是冻结的 teacher 完整 VAE(2.2 VAE 约 1.5GB);如果它与训练激活放不下,请使用 `--low_vram`。
|
||||
|
||||
---
|
||||
|
||||
## 二、数据准备
|
||||
|
||||
### 2.1 快速测试数据集
|
||||
|
||||
我们提供了一个测试的数据集,其中包含若干训练数据。
|
||||
|
||||
```bash
|
||||
# 下载官方示例数据集
|
||||
modelscope download --dataset PAI/X-Fun-Videos-Demo --local_dir ./datasets/X-Fun-Videos-Demo
|
||||
```
|
||||
|
||||
### 2.2 数据集结构
|
||||
|
||||
```
|
||||
📦 datasets/
|
||||
├── 📂 my_dataset/
|
||||
│ ├── 📂 train/
|
||||
│ │ ├── 📄 video001.mp4
|
||||
│ │ ├── 📄 video002.mp4
|
||||
│ │ └── 📄 ...
|
||||
│ └── 📄 metadata.json
|
||||
```
|
||||
|
||||
### 2.3 metadata.json 格式
|
||||
|
||||
**相对路径格式**(示例格式):
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "train/video001.mp4",
|
||||
"text": "A beautiful sunset over the ocean, golden hour lighting",
|
||||
"type": "video",
|
||||
"width": 1024,
|
||||
"height": 1024
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
**绝对路径格式**:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "/mnt/data/videos/sunset.mp4",
|
||||
"text": "A beautiful sunset over the ocean",
|
||||
"type": "video",
|
||||
"width": 1024,
|
||||
"height": 1024
|
||||
}
|
||||
]
|
||||
```
|
||||
|
||||
**关键字段说明**:
|
||||
- `file_path`:视频路径(相对或绝对路径)
|
||||
- `text`:视频描述(TAE 损失不使用,仅为 meta 格式兼容而保留)
|
||||
- `type`:数据类型,固定为 `"video"`
|
||||
- `width` / `height`:视频宽高(**最好提供**,用于分桶训练)。
|
||||
- 可以使用 `scripts/process_json_add_width_and_height.py` 文件对无 width 与 height 字段的 json 进行提取。
|
||||
|
||||
### 2.4 相对路径与绝对路径使用方案
|
||||
|
||||
**相对路径**:
|
||||
|
||||
```bash
|
||||
export DATASET_NAME="datasets/X-Fun-Videos-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Videos-Demo/metadata.json"
|
||||
```
|
||||
|
||||
**绝对路径**:
|
||||
|
||||
```bash
|
||||
export DATASET_NAME=""
|
||||
export DATASET_META_NAME="/mnt/data/metadata.json"
|
||||
```
|
||||
|
||||
> 💡 **建议**:如果数据集较小且存储在本地,推荐使用相对路径;如果数据集存储在外部存储(如 NAS、OSS)或多个机器共享存储,推荐使用绝对路径。
|
||||
|
||||
---
|
||||
|
||||
## 三、TAE 训练
|
||||
|
||||
### 3.1 下载预训练模型
|
||||
|
||||
训练脚本只需要**完整 VAE 权重**(用作冻结的 teacher),它们随模型目录一起提供:
|
||||
|
||||
```bash
|
||||
mkdir -p models/Diffusion_Transformer
|
||||
|
||||
# taew2_2 家族(Wan2.2 TI2V-5B,48ch latent,包含 Wan2.2_VAE.pth)
|
||||
modelscope download --model Wan-AI/Wan2.2-TI2V-5B --local_dir models/Diffusion_Transformer/Wan2.2-TI2V-5B
|
||||
|
||||
# taew2_1 家族(Wan2.1,16ch latent,包含 Wan2.1_VAE.pth)
|
||||
# modelscope download --model Wan-AI/Wan2.1-T2V-14B --local_dir models/Diffusion_Transformer/Wan2.1-T2V-14B
|
||||
```
|
||||
|
||||
可选:下载官方发布的 TAE 权重进行热启动(warm-start),而不是从头训练:
|
||||
|
||||
```bash
|
||||
# 来自 https://github.com/madebyollin/taehv
|
||||
wget https://github.com/madebyollin/taehv/raw/main/taew2_2.safetensors
|
||||
# wget https://github.com/madebyollin/taehv/raw/main/taew2_1.safetensors
|
||||
```
|
||||
|
||||
### 3.2 快速开始
|
||||
|
||||
**Wan2.2 TI2V-5B / Fun-2.2VAE(taew2_2)训练示例**:
|
||||
|
||||
```bash
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Wan2.2-TI2V-5B"
|
||||
export DATASET_NAME="datasets/X-Fun-Videos-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Videos-Demo/metadata.json"
|
||||
# 可选:用官方发布的 TAE 权重热启动,而不是从头训练。
|
||||
export TAE_PATH="models/Diffusion_Transformer/taew2_2.safetensors"
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --mixed_precision="bf16" scripts/taehv/train_taehv.py \
|
||||
--config_path="config/wan2.2/wan_civitai_5b.yaml" \
|
||||
--pretrained_model_name_or_path=$MODEL_NAME \
|
||||
--tae_path=$TAE_PATH \
|
||||
--train_data_dir=$DATASET_NAME \
|
||||
--train_data_meta=$DATASET_META_NAME \
|
||||
--video_sample_size=512 \
|
||||
--video_sample_stride=1 \
|
||||
--video_sample_n_frames=33 \
|
||||
--train_batch_size=1 \
|
||||
--gradient_accumulation_steps=1 \
|
||||
--dataloader_num_workers=4 \
|
||||
--num_train_epochs=100 \
|
||||
--checkpointing_steps=500 \
|
||||
--learning_rate=1e-04 \
|
||||
--lr_scheduler="constant_with_warmup" \
|
||||
--lr_warmup_steps=100 \
|
||||
--latent_loss_weight=1.0 \
|
||||
--seed=42 \
|
||||
--output_dir="output_dir_taehv_w2.2" \
|
||||
--mixed_precision="bf16" \
|
||||
--adam_weight_decay=1e-2 \
|
||||
--adam_epsilon=1e-08 \
|
||||
--vae_mini_batch=1 \
|
||||
--max_grad_norm=1.0 \
|
||||
--random_hw_adapt \
|
||||
--enable_bucket \
|
||||
--trainable_modules "." \
|
||||
--resume_from_checkpoint=latest
|
||||
```
|
||||
|
||||
**Wan2.1 / Wan2.2 14B(taew2_1)训练示例**:
|
||||
|
||||
与上面相同,仅做如下修改:
|
||||
|
||||
```bash
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Wan2.1-T2V-14B"
|
||||
export TAE_PATH="taew2_1.safetensors"
|
||||
# ...
|
||||
--config_path="config/wan2.1/wan_civitai.yaml" \
|
||||
--output_dir="output_dir_taehv_w2.1" \
|
||||
# ...
|
||||
```
|
||||
|
||||
### 3.3 训练常用参数解析
|
||||
|
||||
**关键参数说明**:
|
||||
|
||||
| 参数 | 说明 | 示例值 |
|
||||
|------|------|--------|
|
||||
| `--config_path` | 模型配置 yaml;其 `vae_kwargs.vae_type` 决定 teacher 完整 VAE 家族 | `config/wan2.2/wan_civitai_5b.yaml` |
|
||||
| `--pretrained_model_name_or_path` | 包含完整 VAE 权重的模型目录 | `models/Diffusion_Transformer/Wan2.2-TI2V-5B` |
|
||||
| `--tae_path` | 可选的 TAE 热启动权重(文件或目录)。不填则从头训练 | `taew2_2.safetensors` |
|
||||
| `--tae_arch_variant` | 从头训练时的 TAE decoder 变体:base(`None`)或 `super`(decoder 参数量约 2 倍) | `None` |
|
||||
| `--vae_path` | 可选的完整 VAE(teacher)热加载权重路径 | `None` |
|
||||
| `--freeze_tae_encoder` | 只训练 TAE decoder(decoder-only 蒸馏) | - |
|
||||
| `--use_taehv_sequential` | 以 O(1) 显存的串行模式运行 TAE,而不是并行模式 | - |
|
||||
| `--latent_loss_weight` | latent MSE(TAE latent 对齐完整 VAE latent)相对 pixel L1 的权重 | 1.0 |
|
||||
| `--train_data_dir` | 训练数据目录 | `datasets/X-Fun-Videos-Demo/` |
|
||||
| `--train_data_meta` | 训练数据元文件 | `datasets/X-Fun-Videos-Demo/metadata.json` |
|
||||
| `--train_batch_size` | 每卡批次大小 | 1 |
|
||||
| `--video_sample_size` | 训练分辨率 | 512 |
|
||||
| `--video_sample_stride` | 视频采样步幅 | 1 |
|
||||
| `--video_sample_n_frames` | 采样帧数,**必须为 4k+1**(33、49、81……) | 33 |
|
||||
| `--vae_mini_batch` | teacher VAE 编码时的迷你批次大小 | 1 |
|
||||
| `--gradient_accumulation_steps` | 梯度累积步数 | 1 |
|
||||
| `--dataloader_num_workers` | DataLoader 子进程数 | 4 |
|
||||
| `--num_train_epochs` | 训练 epoch 数 | 100 |
|
||||
| `--checkpointing_steps` | 每 N 步保存 checkpoint | 500 |
|
||||
| `--checkpoints_total_limit` | 最多保留的 checkpoint 数量 | `None` |
|
||||
| `--learning_rate` | 初始学习率 | 1e-4 |
|
||||
| `--lr_scheduler` | 学习率调度器 | `constant_with_warmup` |
|
||||
| `--lr_warmup_steps` | 学习率预热步数 | 100 |
|
||||
| `--use_8bit_adam` / `--use_came` | 可选优化器 | - |
|
||||
| `--use_ema` | 维护 TAE 的 EMA 副本(用于验证与最终保存) | - |
|
||||
| `--seed` | 随机种子 | 42 |
|
||||
| `--output_dir` | 输出目录 | `output_dir_taehv_w2.2` |
|
||||
| `--mixed_precision` | 混合精度:`fp16/bf16` | `bf16` |
|
||||
| `--max_grad_norm` | 梯度裁剪阈值 | 1.0 |
|
||||
| `--enable_bucket` | 启用分桶训练,不裁剪视频,按分辨率分组训练 | - |
|
||||
| `--random_hw_adapt` | 自动缩放视频到一定范围内的随机尺寸 | - |
|
||||
| `--low_vram` | 将 teacher VAE 放在 CPU,仅在编码时搬上 GPU | - |
|
||||
| `--trainable_modules` | 可训练模块(`"."` 表示所有模块) | `"."` |
|
||||
| `--trainable_modules_low_learning_rate` | 以 lr/2 训练的模块 | `[]` |
|
||||
| `--resume_from_checkpoint` | 恢复训练路径,使用 `"latest"` 自动选择最新 checkpoint | `latest` |
|
||||
| `--validation_steps` / `--validation_epochs` | 每 N 步 / 每 N 个 epoch 执行一次验证 | 2000 / 5 |
|
||||
| `--validation_paths` | 用于重建对比验证的视频路径 | `"asset/1.mp4"` |
|
||||
|
||||
**Sample Size 配置指南**:
|
||||
- `video_sample_size` 表示训练分辨率;当启用 `random_hw_adapt` 时,表示分辨率的最小值。
|
||||
- `video_sample_n_frames` 必须满足 `4k+1`(如 33、49、81),因为完整 VAE 与 TAE 都是因果 4 倍时间压缩。
|
||||
|
||||
### 3.4 训练验证
|
||||
|
||||
你可以配置验证参数,在训练过程中定期用 TAE 和完整 VAE 分别重建测试视频,直观监控重建质量。
|
||||
|
||||
| 参数 | 说明 | 推荐值 |
|
||||
|------|------|--------|
|
||||
| `--validation_steps` | 每 N 步执行一次验证 | 2000 |
|
||||
| `--validation_epochs` | 每 N 个 epoch 执行一次验证 | 5 |
|
||||
| `--validation_paths` | 验证视频路径 | `"asset/1.mp4"` |
|
||||
|
||||
```bash
|
||||
--validation_paths "asset/1.mp4" \
|
||||
--validation_steps=2000 \
|
||||
--validation_epochs=5
|
||||
```
|
||||
|
||||
**注意事项**:
|
||||
- 验证会为每个样本在 `output_dir/sample/` 保存三个视频:`*_input.mp4`(缩放后的输入)、`*_taehv.mp4`(TAE 重建)、`*_fullvae.mp4`(完整 VAE 重建,供参考对比)。
|
||||
- 启用 `--use_ema` 时,验证使用 EMA 权重。
|
||||
|
||||
### 3.5 训练技巧
|
||||
|
||||
- **热启动 vs 从头训练**:官方发布的 TAE 权重已经蒸馏得很好;做领域适配时通常直接从 `taew2_x.safetensors` 热启动、用小学习率(1e-5)微调即可。从头训练可以收敛,但需要多得多的数据/步数。
|
||||
- **损失平衡**:`latent_loss_weight=1.0` 用于保持 TAE latent 与扩散 latent 空间对齐。设为 `0.0` 则是纯像素重建(如果你会在采样流程中使用 TAE latent,不推荐)。
|
||||
- **Decoder-only 蒸馏**:加上 `--freeze_tae_encoder` 只提升解码质量。
|
||||
- **显存**:teacher 完整 VAE 是主要的显存消耗者。使用 `--low_vram` 可以将其放在 CPU、仅在编码时搬上 GPU;也可以降低 `--video_sample_n_frames` / `--video_sample_size`。
|
||||
- **串行 TAE**:`--use_taehv_sequential` 以速度换显存,激活显存与视频长度无关(O(1))。
|
||||
- **EMA**:推荐开启 `--use_ema` 作为最终交付物;最终保存的 `taehv` 目录里是 EMA 权重。
|
||||
|
||||
### 3.6 多机分布式训练
|
||||
|
||||
**适合场景**:大规模数据集、需要更快的训练速度
|
||||
|
||||
假设有 2 台机器,每台 8 张 GPU:
|
||||
|
||||
**机器 0(Master)**:
|
||||
```bash
|
||||
export MASTER_ADDR="192.168.1.100" # Master 机器 IP
|
||||
export MASTER_PORT=10086
|
||||
export WORLD_SIZE=2 # 机器总数
|
||||
export NUM_PROCESS=16 # 总进程数 = 机器数 × 8
|
||||
export RANK=0 # 当前机器 rank(0 或 1)
|
||||
# 无 RDMA 时:
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --mixed_precision="bf16" --main_process_ip=$MASTER_ADDR --main_process_port=$MASTER_PORT --num_machines=$WORLD_SIZE --num_processes=$NUM_PROCESS --machine_rank=$RANK scripts/taehv/train_taehv.py \
|
||||
<与快速开始相同的训练参数>
|
||||
```
|
||||
|
||||
**机器 1(Worker)**:使用相同命令,但 `export RANK=1`。
|
||||
|
||||
**注意事项**:
|
||||
- 无 RDMA 时添加 `NCCL_IB_DISABLE=1` 与 `NCCL_P2P_DISABLE=1`。
|
||||
- 所有机器必须能访问相同的数据/模型路径(NFS/共享存储)。
|
||||
|
||||
---
|
||||
|
||||
## 四、推理测试
|
||||
|
||||
### 4.1 Checkpoint 目录结构
|
||||
|
||||
每个 checkpoint 写入 `output_dir/checkpoint-{step}/`,结构如下:
|
||||
|
||||
```
|
||||
📦 output_dir_taehv_w2.2/
|
||||
├── 📂 checkpoint-500/
|
||||
│ ├── 📂 taehv/ # TAE 权重 + config.json(save_pretrained 格式)
|
||||
│ ├── 📂 taehv_ema/ # 仅当开启 --use_ema
|
||||
│ └── 📄 sampler_pos_start.pkl
|
||||
├── 📂 sample/ # 验证视频
|
||||
└── 📂 logs/ # tensorboard
|
||||
```
|
||||
|
||||
`taehv` 子目录是标准的 diffusers 目录 checkpoint,可以被 `AutoencoderTinyWan.from_pretrained` 直接加载。
|
||||
|
||||
### 4.2 在 Predict 脚本中使用训练好的 TAE
|
||||
|
||||
将任意 TAE predict 脚本中的 `tae_path` 指向你的 checkpoint 的 `taehv` 子目录即可:
|
||||
|
||||
| 脚本 | 家族 |
|
||||
|------|------|
|
||||
| `examples/wan2.2/predict_ti2v_tae.py` | taew2_2 |
|
||||
| `examples/wan2.2_fun/predict_t2v_2.2vae_tae.py` | taew2_2 |
|
||||
| `examples/wan2.2_fun/predict_i2v_2.2vae_tae.py` | taew2_2 |
|
||||
| `examples/wan2.1/predict_t2v_tae.py` | taew2_1 |
|
||||
| `examples/wan2.1/predict_i2v_tae.py` | taew2_1 |
|
||||
|
||||
```python
|
||||
# 例如 examples/wan2.2_fun/predict_t2v_2.2vae_tae.py 中
|
||||
tae_path = "output_dir_taehv_w2.2/checkpoint-500/taehv"
|
||||
```
|
||||
|
||||
训练好的 TAE 与官方发布的 TAE 完全互换:它保持与完整 VAE 相同的 latent 空间,因此可以像 `taew2_2.safetensors` 一样在扩散 pipeline 中用于快速预览解码。
|
||||
|
||||
---
|
||||
|
||||
## 五、更多资源
|
||||
|
||||
- **TAE 参考实现**:https://github.com/madebyollin/taehv
|
||||
- **官方 GitHub**:https://github.com/aigc-apps/VideoX-Fun
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,38 @@
|
||||
export MODEL_NAME="models/Diffusion_Transformer/Wan2.2-TI2V-5B"
|
||||
export DATASET_NAME="datasets/X-Fun-Videos-Demo/"
|
||||
export DATASET_META_NAME="datasets/X-Fun-Videos-Demo/metadata.json"
|
||||
export TAE_PATH="models/Diffusion_Transformer/taew2_2.safetensors"
|
||||
# NCCL_IB_DISABLE=1 and NCCL_P2P_DISABLE=1 are used in multi nodes without RDMA.
|
||||
# export NCCL_IB_DISABLE=1
|
||||
# export NCCL_P2P_DISABLE=1
|
||||
NCCL_DEBUG=INFO
|
||||
|
||||
accelerate launch --mixed_precision="bf16" scripts/taehv/train_taehv.py \
|
||||
--config_path="config/wan2.2/wan_civitai_5b.yaml" \
|
||||
--pretrained_model_name_or_path=$MODEL_NAME \
|
||||
--tae_path=$TAE_PATH \
|
||||
--train_data_dir=$DATASET_NAME \
|
||||
--train_data_meta=$DATASET_META_NAME \
|
||||
--video_sample_size=512 \
|
||||
--video_sample_stride=1 \
|
||||
--video_sample_n_frames=33 \
|
||||
--train_batch_size=1 \
|
||||
--gradient_accumulation_steps=1 \
|
||||
--dataloader_num_workers=4 \
|
||||
--num_train_epochs=100 \
|
||||
--checkpointing_steps=500 \
|
||||
--learning_rate=1e-04 \
|
||||
--lr_scheduler="constant_with_warmup" \
|
||||
--lr_warmup_steps=100 \
|
||||
--latent_loss_weight=1.0 \
|
||||
--seed=42 \
|
||||
--output_dir="output_dir_taehv_w2.2" \
|
||||
--mixed_precision="bf16" \
|
||||
--adam_weight_decay=1e-2 \
|
||||
--adam_epsilon=1e-08 \
|
||||
--vae_mini_batch=1 \
|
||||
--max_grad_norm=1.0 \
|
||||
--random_hw_adapt \
|
||||
--enable_bucket \
|
||||
--trainable_modules "." \
|
||||
--resume_from_checkpoint=latest
|
||||
@@ -56,7 +56,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import BatchSampler, Dataset, RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -78,6 +77,7 @@ from videox_fun.models import (AutoencoderKLWan, CLIPModel,
|
||||
WanTransformer3DModel)
|
||||
from videox_fun.pipeline import WanI2VPipeline, WanPipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
@@ -920,14 +920,17 @@ def main():
|
||||
generator_transformer3d = TurboWanTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
real_score_transformer3d = WanTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
fake_score_transformer3d = TurboWanTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set generator_transformer3d to trainable
|
||||
@@ -1028,7 +1031,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = WanTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1614,7 +1618,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1686,6 +1690,10 @@ def main():
|
||||
|
||||
for epoch in range(first_epoch, args.num_train_epochs):
|
||||
train_dmd_loss = 0.0
|
||||
# Number of generator backward contributions since the last log flush; the
|
||||
# generator only backprops every gen_update_interval batches, so its metrics
|
||||
# must be averaged by contribution count, not by gradient_accumulation_steps.
|
||||
train_gen_log_count = 0
|
||||
train_denoising_loss = 0.0
|
||||
batch_sampler.sampler.generator = torch.Generator().manual_seed(args.seed + epoch)
|
||||
for step, batch in enumerate(train_dataloader):
|
||||
@@ -1943,7 +1951,17 @@ def main():
|
||||
text_encoder.to('cpu')
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
with accelerator.accumulate(generator_transformer3d):
|
||||
generator_update = step % args.gen_update_interval == 0
|
||||
# Enter the generator's accumulation context only on batches that actually
|
||||
# backprop through the generator. Entering it on every batch would advance
|
||||
# the accumulation counter gen_update_interval times faster than real
|
||||
# generator gradients are produced; whenever gcd(gradient_accumulation_steps,
|
||||
# gen_update_interval) > 1 the sync flag would then never coincide with a
|
||||
# generator-update batch and optimizer.step() would silently never fire.
|
||||
generator_accumulate_ctx = (
|
||||
accelerator.accumulate(generator_transformer3d) if generator_update else contextlib.nullcontext()
|
||||
)
|
||||
with generator_accumulate_ctx:
|
||||
def get_sigmas(timesteps, n_dim=4, dtype=torch.float32):
|
||||
sigmas = noise_scheduler.sigmas.to(device=accelerator.device, dtype=dtype)
|
||||
schedule_timesteps = noise_scheduler.timesteps.to(accelerator.device)
|
||||
@@ -2019,7 +2037,7 @@ def main():
|
||||
|
||||
# --- Main Training Logic ---
|
||||
bsz, channel, num_frames, height, width = target_shape
|
||||
if step % args.gen_update_interval == 0:
|
||||
if generator_update: # generator_update computed before the accumulate ctx above
|
||||
generator_noise = torch.randn(target_shape, device=accelerator.device, generator=torch_rng, dtype=weight_dtype)
|
||||
num_denoising_steps = len(denoising_step_list)
|
||||
final_step_index = generate_and_sync_list(num_denoising_steps, device=generator_noise.device)[0]
|
||||
@@ -2162,7 +2180,8 @@ def main():
|
||||
reduction="mean"
|
||||
)
|
||||
avg_dmd_loss = accelerator.gather(dmd_loss.repeat(args.train_batch_size)).mean()
|
||||
train_dmd_loss += avg_dmd_loss.item() / args.gradient_accumulation_steps
|
||||
train_dmd_loss += avg_dmd_loss.item()
|
||||
train_gen_log_count += 1
|
||||
|
||||
if args.low_vram:
|
||||
real_score_transformer3d = real_score_transformer3d.to("cpu")
|
||||
@@ -2282,8 +2301,9 @@ def main():
|
||||
|
||||
progress_bar.update(1)
|
||||
global_step += 1
|
||||
accelerator.log({"train_denoising_loss": train_denoising_loss, "train_dmd_loss": train_dmd_loss}, step=global_step)
|
||||
accelerator.log({"train_denoising_loss": train_denoising_loss, "train_dmd_loss": train_dmd_loss / max(train_gen_log_count, 1)}, step=global_step)
|
||||
train_dmd_loss = 0.0
|
||||
train_gen_log_count = 0
|
||||
train_denoising_loss = 0.0
|
||||
|
||||
if global_step % args.checkpointing_steps == 0:
|
||||
@@ -2312,24 +2332,34 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
fake_score_save_path = os.path.join(save_path, "fake_score")
|
||||
accelerator.save_state(save_path)
|
||||
accelerator_fake_score_transformer3d.save_state(fake_score_save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
fake_score_save_path = os.path.join(save_path, "fake_score")
|
||||
accelerator.save_state(save_path)
|
||||
accelerator_fake_score_transformer3d.save_state(fake_score_save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"denoising_loss": denoising_loss.detach().item(), "dmd_loss": dmd_loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -2338,18 +2368,24 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
+85
-49
@@ -53,7 +53,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -73,6 +72,8 @@ from videox_fun.models import (AutoencoderKLWan, CLIPModel, WanT5EncoderModel,
|
||||
WanTransformer3DModel)
|
||||
from videox_fun.pipeline import WanI2VPipeline, WanPipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.fsdp_ema import FSDPEMA
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
@@ -909,6 +910,7 @@ def main():
|
||||
transformer3d = WanTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -961,14 +963,20 @@ def main():
|
||||
# Create EMA for the transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_transformer3d = WanTransformer3DModel.from_pretrained(
|
||||
ema_module = WanTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
).to(weight_dtype)
|
||||
|
||||
ema_transformer3d = EMAModel(ema_transformer3d.parameters(), model_cls=WanTransformer3DModel, model_config=ema_transformer3d.config)
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
if args.use_fsdp:
|
||||
# The EMA copy gets the same FSDP wrap as the live model so that
|
||||
# every local shard of the copy pairs 1:1 with the live shard.
|
||||
ema_transformer3d = FSDPEMA(ema_module, source=transformer3d, accelerator=accelerator, fsdp_plugin=fsdp_plugin)
|
||||
else:
|
||||
ema_module = ema_module.to(weight_dtype)
|
||||
ema_transformer3d = EMAModel(ema_module.parameters(), model_cls=WanTransformer3DModel, model_config=ema_module.config)
|
||||
|
||||
# `accelerate` 0.16.0 will have better support for customized saving
|
||||
if version.parse(accelerate.__version__) >= version.parse("0.16.0"):
|
||||
@@ -985,8 +993,13 @@ def main():
|
||||
|
||||
with open(os.path.join(output_dir, "sampler_pos_start.pkl"), 'wb') as file:
|
||||
pickle.dump([batch_sampler.sampler._pos_start, first_epoch], file)
|
||||
if args.use_ema:
|
||||
# Every rank joins the FULL_STATE_DICT all-gather inside.
|
||||
ema_transformer3d.save_pretrained(os.path.join(output_dir, "transformer_ema"))
|
||||
|
||||
def load_model_hook(models, input_dir):
|
||||
if args.use_ema:
|
||||
ema_transformer3d.load_pretrained(os.path.join(input_dir, "transformer_ema"))
|
||||
pkl_path = os.path.join(input_dir, "sampler_pos_start.pkl")
|
||||
if os.path.exists(pkl_path):
|
||||
with open(pkl_path, 'rb') as file:
|
||||
@@ -1013,7 +1026,8 @@ def main():
|
||||
_, ema_kwargs = WanTransformer3DModel.load_config(ema_path, return_unused_kwargs=True)
|
||||
load_model = WanTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs'])
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=WanTransformer3DModel, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -1028,7 +1042,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = WanTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1463,7 +1478,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1841,29 +1856,39 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1872,31 +1897,42 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the UNet parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_transformer3d.store(transformer3d.parameters())
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original transformer3d parameters.
|
||||
ema_transformer3d.restore(transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
if args.use_ema and args.use_fsdp:
|
||||
# Under FSDP every rank must write its own shards, and the shards only
|
||||
# exist while the model is still wrapped, so this runs before the
|
||||
# `unwrap_model` below.
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
if accelerator.is_main_process:
|
||||
transformer3d = unwrap_model(transformer3d)
|
||||
if args.use_ema:
|
||||
if args.use_ema and not args.use_fsdp:
|
||||
ema_transformer3d.copy_to(transformer3d.parameters())
|
||||
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
|
||||
+122
-57
@@ -50,13 +50,9 @@ from einops import rearrange
|
||||
from omegaconf import OmegaConf
|
||||
from packaging import version
|
||||
from PIL import Image
|
||||
from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
FullOptimStateDictConfig, FullStateDictConfig, ShardedOptimStateDictConfig,
|
||||
ShardedStateDictConfig)
|
||||
from torch.utils.data import BatchSampler, Dataset, RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -77,6 +73,7 @@ from videox_fun.models import (AutoencoderKLWan, CLIPModel, WanT5EncoderModel,
|
||||
WanTransformer3DModel)
|
||||
from videox_fun.pipeline import WanI2VPipeline, WanPipeline
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
@@ -746,6 +743,23 @@ def parse_args():
|
||||
action="store_true",
|
||||
help="whether to use randomize timesteps indices in training.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--index_jitter_ratio",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Symmetric jitter budget (fraction of the neighboring gap) applied to the "
|
||||
"denoising step indices when --randomize_step_indices is enabled.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--flow_euler_rollout",
|
||||
action="store_true",
|
||||
help="Simulate the normal flow-matching inference rollout in the generator's multi-step "
|
||||
"self-rollout (LightX2V-style): keep the model prediction in flow/velocity space and "
|
||||
"advance to the next noise level with a deterministic Euler ODE step "
|
||||
"(x_next = x_t + (sigma_next - sigma_t) * v), instead of converting the prediction "
|
||||
"to x0 and re-noising with fresh noise. The final step still converts to x0 since "
|
||||
"the DMD objective is defined on x0.",
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--dfd",
|
||||
@@ -981,14 +995,17 @@ def main():
|
||||
generator_transformer3d = WanTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
real_score_transformer3d = WanTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
fake_score_transformer3d = WanTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set generator_transformer3d to trainable
|
||||
@@ -1119,7 +1136,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = WanTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1271,7 +1289,7 @@ def main():
|
||||
args.random_hw_adapt = False
|
||||
|
||||
# Get the dataset
|
||||
# DFD needs paired videos for the teacher-score input, everything else reuses the DMD data path.
|
||||
# DFD needs paired videos for the teacher-score input; everything else reuses the DMD data path.
|
||||
need_real_video = args.train_mode != "normal" or args.dfd
|
||||
if need_real_video:
|
||||
train_dataset = ImageVideoDataset(
|
||||
@@ -1710,7 +1728,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1791,6 +1809,10 @@ def main():
|
||||
train_ca_scale = 0.0
|
||||
train_dm_scale = 0.0
|
||||
train_latent_std = 0.0
|
||||
# Number of generator backward contributions since the last log flush; the
|
||||
# generator only backprops every gen_update_interval batches, so its metrics
|
||||
# must be averaged by contribution count, not by gradient_accumulation_steps.
|
||||
train_gen_log_count = 0
|
||||
batch_sampler.sampler.generator = torch.Generator().manual_seed(args.seed + epoch)
|
||||
for step, batch in enumerate(train_dataloader):
|
||||
generator_update = step % args.gen_update_interval == 0
|
||||
@@ -2003,7 +2025,8 @@ def main():
|
||||
vae.to(accelerator.device)
|
||||
with torch.no_grad():
|
||||
real_latents = vae.encode(pixel_values)[0].sample()
|
||||
target_shape = real_latents.size()
|
||||
if dfd_active:
|
||||
target_shape = real_latents.size()
|
||||
|
||||
if args.low_vram:
|
||||
vae.to('cpu')
|
||||
@@ -2060,7 +2083,16 @@ def main():
|
||||
text_encoder.to('cpu')
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
with accelerator.accumulate(generator_transformer3d):
|
||||
# Enter the generator's accumulation context only on batches that actually
|
||||
# backprop through the generator. Entering it on every batch would advance
|
||||
# the accumulation counter gen_update_interval times faster than real
|
||||
# generator gradients are produced; whenever gcd(gradient_accumulation_steps,
|
||||
# gen_update_interval) > 1 the sync flag would then never coincide with a
|
||||
# generator-update batch and optimizer.step() would silently never fire.
|
||||
generator_accumulate_ctx = (
|
||||
accelerator.accumulate(generator_transformer3d) if generator_update else contextlib.nullcontext()
|
||||
)
|
||||
with generator_accumulate_ctx:
|
||||
def get_sigmas(timesteps, n_dim=4, dtype=torch.float32):
|
||||
sigmas = noise_scheduler.sigmas.to(device=accelerator.device, dtype=dtype)
|
||||
schedule_timesteps = noise_scheduler.timesteps.to(accelerator.device)
|
||||
@@ -2201,12 +2233,13 @@ def main():
|
||||
y=inpaint_latents if args.train_mode != "normal" else None,
|
||||
clip_fea=clip_context if args.train_mode != "normal" else None,
|
||||
)
|
||||
generator_pred = convert_flow_pred_to_x0(
|
||||
scheduler=noise_scheduler,
|
||||
flow_pred=generator_pred,
|
||||
xt=generator_noise,
|
||||
timestep=timestep
|
||||
)
|
||||
if not args.flow_euler_rollout or is_final_step:
|
||||
generator_pred = convert_flow_pred_to_x0(
|
||||
scheduler=noise_scheduler,
|
||||
flow_pred=generator_pred,
|
||||
xt=generator_noise,
|
||||
timestep=timestep
|
||||
)
|
||||
|
||||
if is_final_step:
|
||||
# Generator's current-step noise level t, used to bound tau_CA in Decoupled DMD.
|
||||
@@ -2216,11 +2249,23 @@ def main():
|
||||
next_timestep = denoising_step_list[index + 1] * torch.ones(
|
||||
generator_noise.shape[:1], dtype=torch.long, device=generator_noise.device
|
||||
)
|
||||
generator_noise = add_noise(
|
||||
generator_pred,
|
||||
torch.randn(generator_pred.shape, dtype=generator_pred.dtype, device=generator_pred.device, generator=torch_rng),
|
||||
next_timestep
|
||||
)
|
||||
if args.flow_euler_rollout:
|
||||
# Mimic the normal flow-matching inference rollout (LightX2V-style): keep
|
||||
# the prediction in flow/velocity space and advance to the next noise level
|
||||
# with a deterministic Euler ODE step, no x0 conversion / fresh re-noising.
|
||||
# x_next = x_t - sigma_t * v + sigma_n * v = x_t + (sigma_n - sigma_t) * v,
|
||||
# matching LightX2V WanStepDistillScheduler.step_post (computed in fp32).
|
||||
sigma_t = get_sigmas(timestep, n_dim=generator_noise.ndim, dtype=torch.float32)
|
||||
sigma_next = get_sigmas(next_timestep, n_dim=generator_noise.ndim, dtype=torch.float32)
|
||||
generator_noise = (
|
||||
generator_noise.float() + (sigma_next - sigma_t) * generator_pred.float()
|
||||
).to(generator_noise.dtype)
|
||||
else:
|
||||
generator_noise = add_noise(
|
||||
generator_pred,
|
||||
torch.randn(generator_pred.shape, dtype=generator_pred.dtype, device=generator_pred.device, generator=torch_rng),
|
||||
next_timestep
|
||||
)
|
||||
|
||||
indices = idx_sampling(bsz, generator=torch_rng, device=accelerator.device).long().cpu()
|
||||
generator_timestep = noise_scheduler.timesteps[indices].to(device=accelerator.device)
|
||||
@@ -2418,27 +2463,29 @@ def main():
|
||||
reduction="mean"
|
||||
)
|
||||
avg_dmd_loss = accelerator.gather(dmd_loss.repeat(args.train_batch_size)).mean()
|
||||
train_dmd_loss += avg_dmd_loss.item() / args.gradient_accumulation_steps
|
||||
train_dmd_loss += avg_dmd_loss.item()
|
||||
train_gen_log_count += 1
|
||||
|
||||
monitor = accelerator.gather(
|
||||
torch.stack([ca_scale, dm_scale, generator_pred.float().std()])[None]
|
||||
).mean(dim=0)
|
||||
train_ca_scale += monitor[0].item() / args.gradient_accumulation_steps
|
||||
train_dm_scale += monitor[1].item() / args.gradient_accumulation_steps
|
||||
train_latent_std += monitor[2].item() / args.gradient_accumulation_steps
|
||||
train_ca_scale += monitor[0].item()
|
||||
train_dm_scale += monitor[1].item()
|
||||
train_latent_std += monitor[2].item()
|
||||
|
||||
if args.low_vram:
|
||||
real_score_transformer3d = real_score_transformer3d.to("cpu")
|
||||
fake_score_transformer3d = fake_score_transformer3d.to("cpu")
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
accelerator.backward(dmd_loss)
|
||||
generator_loss = dmd_loss
|
||||
accelerator.backward(generator_loss)
|
||||
if accelerator.sync_gradients:
|
||||
accelerator.clip_grad_norm_(trainable_params, args.max_grad_norm)
|
||||
optimizer.step()
|
||||
lr_scheduler.step()
|
||||
optimizer.zero_grad()
|
||||
|
||||
|
||||
if args.low_vram:
|
||||
fake_score_transformer3d = fake_score_transformer3d.to(accelerator.device)
|
||||
torch.cuda.empty_cache()
|
||||
@@ -2545,11 +2592,12 @@ def main():
|
||||
|
||||
progress_bar.update(1)
|
||||
global_step += 1
|
||||
tracker_logs = {"train_denoising_loss": train_denoising_loss, "train_dmd_loss": train_dmd_loss}
|
||||
tracker_logs["train_ca_scale"] = train_ca_scale
|
||||
tracker_logs["train_dm_scale"] = train_dm_scale
|
||||
gen_log_div = max(train_gen_log_count, 1)
|
||||
tracker_logs = {"train_denoising_loss": train_denoising_loss, "train_dmd_loss": train_dmd_loss / gen_log_div}
|
||||
tracker_logs["train_ca_scale"] = train_ca_scale / gen_log_div
|
||||
tracker_logs["train_dm_scale"] = train_dm_scale / gen_log_div
|
||||
tracker_logs["train_ca_dm_ratio"] = train_ca_scale / (train_dm_scale + 1e-12)
|
||||
tracker_logs["train_latent_std"] = train_latent_std
|
||||
tracker_logs["train_latent_std"] = train_latent_std / gen_log_div
|
||||
if args.dfd:
|
||||
tracker_logs["train_dfd_real_replace"] = train_dfd_real_replace
|
||||
dfd_real_replace_now = train_dfd_real_replace
|
||||
@@ -2560,6 +2608,7 @@ def main():
|
||||
train_ca_scale = 0.0
|
||||
train_dm_scale = 0.0
|
||||
train_latent_std = 0.0
|
||||
train_gen_log_count = 0
|
||||
|
||||
if global_step % args.checkpointing_steps == 0:
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
@@ -2587,24 +2636,34 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
fake_score_save_path = os.path.join(save_path, "fake_score")
|
||||
accelerator.save_state(save_path)
|
||||
accelerator_fake_score_transformer3d.save_state(fake_score_save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
fake_score_save_path = os.path.join(save_path, "fake_score")
|
||||
accelerator.save_state(save_path)
|
||||
accelerator_fake_score_transformer3d.save_state(fake_score_save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
if args.dfd:
|
||||
logs = {"lr": (lr_scheduler if generator_update else fake_score_lr_scheduler).get_last_lr()[0], "denoising_loss": denoising_loss.detach().item()}
|
||||
@@ -2623,18 +2682,24 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -56,7 +56,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import BatchSampler, Dataset, RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -80,6 +79,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
@@ -749,6 +749,23 @@ def parse_args():
|
||||
action="store_true",
|
||||
help="whether to use randomize timesteps indices in training.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--index_jitter_ratio",
|
||||
type=float,
|
||||
default=0.3,
|
||||
help="Symmetric jitter budget (fraction of the neighboring gap) applied to the "
|
||||
"denoising step indices when --randomize_step_indices is enabled.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--flow_euler_rollout",
|
||||
action="store_true",
|
||||
help="Simulate the normal flow-matching inference rollout in the generator's multi-step "
|
||||
"self-rollout (LightX2V-style): keep the model prediction in flow/velocity space and "
|
||||
"advance to the next noise level with a deterministic Euler ODE step "
|
||||
"(x_next = x_t + (sigma_next - sigma_t) * v), instead of converting the prediction "
|
||||
"to x0 and re-noising with fresh noise. The final step still converts to x0 since "
|
||||
"the DMD objective is defined on x0.",
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--dfd",
|
||||
@@ -767,6 +784,13 @@ def parse_args():
|
||||
default=0,
|
||||
help="Switch on DFD from this global_step onward; earlier steps run plain DMD.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--decoupled_dmd",
|
||||
action="store_true",
|
||||
help="Use Decoupled DMD (arXiv:2511.22677): decompose the DMD gradient into a CFG Augmentation "
|
||||
"term re-noised at tau_CA cleaner than the generator's current step and a Distribution "
|
||||
"Matching term re-noised over the full noise range (Decoupled-Hybrid schedule).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--generator_transformer_path",
|
||||
type=str,
|
||||
@@ -821,6 +845,14 @@ def main():
|
||||
if args.gen_update_interval <= 0:
|
||||
raise ValueError("--gen_update_interval must be greater than zero.")
|
||||
|
||||
if args.decoupled_dmd:
|
||||
if args.real_guidance_scale <= 1.0:
|
||||
raise ValueError("--real_guidance_scale must be greater than 1.0 to keep the CA term of Decoupled DMD active.")
|
||||
if args.dfd:
|
||||
raise ValueError("Decoupled DMD does not support --dfd.")
|
||||
if any(int(i) <= 1 for i in args.denoising_step_indices_list):
|
||||
print("WARNING: --denoising_step_indices_list contains a step index below 2, where tau_CA degenerates to tau_CA == t.")
|
||||
|
||||
if args.report_to == "wandb" and args.hub_token is not None:
|
||||
raise ValueError(
|
||||
"You cannot use both --report_to=wandb and --hub_token due to a security risk of exposing your token."
|
||||
@@ -1734,7 +1766,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1812,6 +1844,13 @@ def main():
|
||||
train_denoising_loss = 0.0
|
||||
train_dfd_real_replace = 0.0
|
||||
dfd_real_replace_now = 0.0
|
||||
train_ca_scale = 0.0
|
||||
train_dm_scale = 0.0
|
||||
train_latent_std = 0.0
|
||||
# Number of generator backward contributions since the last log flush; the
|
||||
# generator only backprops every gen_update_interval batches, so its metrics
|
||||
# must be averaged by contribution count, not by gradient_accumulation_steps.
|
||||
train_gen_log_count = 0
|
||||
batch_sampler.sampler.generator = torch.Generator().manual_seed(args.seed + epoch)
|
||||
for step, batch in enumerate(train_dataloader):
|
||||
generator_update = step % args.gen_update_interval == 0
|
||||
@@ -2081,7 +2120,16 @@ def main():
|
||||
text_encoder.to('cpu')
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
with accelerator.accumulate(generator_transformer3d):
|
||||
# Enter the generator's accumulation context only on batches that actually
|
||||
# backprop through the generator. Entering it on every batch would advance
|
||||
# the accumulation counter gen_update_interval times faster than real
|
||||
# generator gradients are produced; whenever gcd(gradient_accumulation_steps,
|
||||
# gen_update_interval) > 1 the sync flag would then never coincide with a
|
||||
# generator-update batch and optimizer.step() would silently never fire.
|
||||
generator_accumulate_ctx = (
|
||||
accelerator.accumulate(generator_transformer3d) if generator_update else contextlib.nullcontext()
|
||||
)
|
||||
with generator_accumulate_ctx:
|
||||
def get_sigmas(timesteps, n_dim=4, dtype=torch.float32):
|
||||
sigmas = noise_scheduler.sigmas.to(device=accelerator.device, dtype=dtype)
|
||||
schedule_timesteps = noise_scheduler.timesteps.to(accelerator.device)
|
||||
@@ -2157,6 +2205,8 @@ def main():
|
||||
student_timestep_indices = torch.randint(0, dfd_student_timesteps.numel(), (bsz,), device=accelerator.device, generator=torch_rng)
|
||||
student_noise = torch.randn(target_shape, device=accelerator.device, generator=torch_rng, dtype=real_latents.dtype)
|
||||
student_timestep = dfd_student_timesteps[student_timestep_indices] * 1000
|
||||
# Generator's current-step noise level t, used to bound tau_CA in Decoupled DMD.
|
||||
generator_step_timestep = student_timestep
|
||||
student_input = add_noise(real_latents, student_noise, student_timestep)
|
||||
student_forward_context = contextlib.nullcontext() if generator_update else torch.no_grad()
|
||||
with torch.cuda.amp.autocast(dtype=weight_dtype), torch.cuda.device(device=accelerator.device), student_forward_context:
|
||||
@@ -2220,24 +2270,39 @@ def main():
|
||||
y=inpaint_latents if args.train_mode != "normal" else None,
|
||||
clip_fea=clip_context if args.train_mode != "normal" else None,
|
||||
)
|
||||
generator_pred = convert_flow_pred_to_x0(
|
||||
scheduler=noise_scheduler,
|
||||
flow_pred=generator_pred,
|
||||
xt=generator_noise,
|
||||
timestep=timestep
|
||||
)
|
||||
if not args.flow_euler_rollout or is_final_step:
|
||||
generator_pred = convert_flow_pred_to_x0(
|
||||
scheduler=noise_scheduler,
|
||||
flow_pred=generator_pred,
|
||||
xt=generator_noise,
|
||||
timestep=timestep
|
||||
)
|
||||
|
||||
if is_final_step:
|
||||
# Generator's current-step noise level t, used to bound tau_CA in Decoupled DMD.
|
||||
generator_step_timestep = timestep
|
||||
break
|
||||
|
||||
next_timestep = denoising_step_list[index + 1] * torch.ones(
|
||||
generator_noise.shape[:1], dtype=torch.long, device=generator_noise.device
|
||||
)
|
||||
generator_noise = add_noise(
|
||||
generator_pred,
|
||||
torch.randn(generator_pred.shape, dtype=generator_pred.dtype, device=generator_pred.device, generator=torch_rng),
|
||||
next_timestep
|
||||
)
|
||||
if args.flow_euler_rollout:
|
||||
# Mimic the normal flow-matching inference rollout (LightX2V-style): keep
|
||||
# the prediction in flow/velocity space and advance to the next noise level
|
||||
# with a deterministic Euler ODE step, no x0 conversion / fresh re-noising.
|
||||
# x_next = x_t - sigma_t * v + sigma_n * v = x_t + (sigma_n - sigma_t) * v,
|
||||
# matching LightX2V WanStepDistillScheduler.step_post (computed in fp32).
|
||||
sigma_t = get_sigmas(timestep, n_dim=generator_noise.ndim, dtype=torch.float32)
|
||||
sigma_next = get_sigmas(next_timestep, n_dim=generator_noise.ndim, dtype=torch.float32)
|
||||
generator_noise = (
|
||||
generator_noise.float() + (sigma_next - sigma_t) * generator_pred.float()
|
||||
).to(generator_noise.dtype)
|
||||
else:
|
||||
generator_noise = add_noise(
|
||||
generator_pred,
|
||||
torch.randn(generator_pred.shape, dtype=generator_pred.dtype, device=generator_pred.device, generator=torch_rng),
|
||||
next_timestep
|
||||
)
|
||||
|
||||
indices = idx_sampling(bsz, generator=torch_rng, device=accelerator.device).long().cpu()
|
||||
generator_timestep = noise_scheduler.timesteps[indices].to(device=accelerator.device)
|
||||
@@ -2248,6 +2313,33 @@ def main():
|
||||
generator_timestep
|
||||
).detach().to(accelerator.device, dtype=weight_dtype)
|
||||
|
||||
if args.decoupled_dmd:
|
||||
# Decoupled DMD (arXiv:2511.22677, Sec. 4.3): the CA engine must re-noise at
|
||||
# tau_CA > t, i.e. noise levels cleaner than the generator's current step, so it
|
||||
# only enhances not-yet-resolved (higher-frequency) content. Scheduler timesteps
|
||||
# are ordered from noisy to clean, hence sample indices strictly after t's position.
|
||||
schedule_timesteps = noise_scheduler.timesteps.to(device=accelerator.device)
|
||||
num_schedule_steps = schedule_timesteps.numel()
|
||||
step_positions = torch.argmin(
|
||||
(schedule_timesteps.unsqueeze(0).float() - generator_step_timestep.reshape(-1, 1).float()).abs(),
|
||||
dim=1
|
||||
)
|
||||
# Uniform over the schedule positions cleaner than t, matching how tau_DM is
|
||||
# sampled uniformly over the full set of schedule positions.
|
||||
ca_low = (step_positions + 1).clamp(max=num_schedule_steps - 1)
|
||||
ca_span = num_schedule_steps - ca_low
|
||||
ca_offset = (
|
||||
torch.rand(ca_low.shape, device=accelerator.device, generator=torch_rng) * ca_span
|
||||
).long()
|
||||
ca_positions = (ca_low + ca_offset).clamp(max=num_schedule_steps - 1)
|
||||
ca_timestep = schedule_timesteps[ca_positions]
|
||||
ca_noise = torch.randn(generator_pred.shape, dtype=generator_pred.dtype, device=generator_pred.device, generator=torch_rng)
|
||||
generator_ca_input = add_noise(
|
||||
generator_pred,
|
||||
ca_noise,
|
||||
ca_timestep
|
||||
).detach().to(accelerator.device, dtype=weight_dtype)
|
||||
|
||||
# DFD may feed the frozen teacher the paired real latent instead.
|
||||
real_score_input = generator_denoised_input
|
||||
use_dfd_real = dfd_active and real_latents is not None and torch.rand((), device=accelerator.device, generator=torch_rng).item() < args.dfd_teacher_replace_prob
|
||||
@@ -2297,7 +2389,7 @@ def main():
|
||||
else:
|
||||
fake_score_main = fake_score_main_cond
|
||||
|
||||
# Compute real score
|
||||
# Compute real score (conditional branch always evaluated on the DM input tau_DM)
|
||||
real_score_main_cond = real_score_transformer3d(
|
||||
x=real_score_input,
|
||||
context=prompt_embeds,
|
||||
@@ -2313,29 +2405,82 @@ def main():
|
||||
timestep=generator_timestep
|
||||
)
|
||||
|
||||
real_score_main_uncond = real_score_transformer3d(
|
||||
x=real_score_input,
|
||||
context=neg_prompt_embeds,
|
||||
t=generator_timestep,
|
||||
seq_len=seq_len,
|
||||
y=inpaint_latents if args.train_mode != "normal" else None,
|
||||
clip_fea=clip_context if args.train_mode != "normal" else None,
|
||||
)
|
||||
real_score_main_uncond = convert_flow_pred_to_x0(
|
||||
scheduler=noise_scheduler,
|
||||
flow_pred=real_score_main_uncond,
|
||||
xt=real_score_input,
|
||||
timestep=generator_timestep
|
||||
)
|
||||
if args.decoupled_dmd:
|
||||
# CA term: teacher cond/uncond evaluated at the cleaner re-noise level tau_CA.
|
||||
real_score_ca_cond = real_score_transformer3d(
|
||||
x=generator_ca_input,
|
||||
context=prompt_embeds,
|
||||
t=ca_timestep,
|
||||
seq_len=seq_len,
|
||||
y=inpaint_latents if args.train_mode != "normal" else None,
|
||||
clip_fea=clip_context if args.train_mode != "normal" else None,
|
||||
)
|
||||
real_score_ca_cond = convert_flow_pred_to_x0(
|
||||
scheduler=noise_scheduler,
|
||||
flow_pred=real_score_ca_cond,
|
||||
xt=generator_ca_input,
|
||||
timestep=ca_timestep
|
||||
)
|
||||
|
||||
real_score_main = real_score_main_uncond + (
|
||||
real_score_main_cond - real_score_main_uncond
|
||||
) * args.real_guidance_scale
|
||||
real_score_ca_uncond = real_score_transformer3d(
|
||||
x=generator_ca_input,
|
||||
context=neg_prompt_embeds,
|
||||
t=ca_timestep,
|
||||
seq_len=seq_len,
|
||||
y=inpaint_latents if args.train_mode != "normal" else None,
|
||||
clip_fea=clip_context if args.train_mode != "normal" else None,
|
||||
)
|
||||
real_score_ca_uncond = convert_flow_pred_to_x0(
|
||||
scheduler=noise_scheduler,
|
||||
flow_pred=real_score_ca_uncond,
|
||||
xt=generator_ca_input,
|
||||
timestep=ca_timestep
|
||||
)
|
||||
else:
|
||||
real_score_main_uncond = real_score_transformer3d(
|
||||
x=real_score_input,
|
||||
context=neg_prompt_embeds,
|
||||
t=generator_timestep,
|
||||
seq_len=seq_len,
|
||||
y=inpaint_latents if args.train_mode != "normal" else None,
|
||||
clip_fea=clip_context if args.train_mode != "normal" else None,
|
||||
)
|
||||
real_score_main_uncond = convert_flow_pred_to_x0(
|
||||
scheduler=noise_scheduler,
|
||||
flow_pred=real_score_main_uncond,
|
||||
xt=real_score_input,
|
||||
timestep=generator_timestep
|
||||
)
|
||||
|
||||
real_score_main = real_score_main_uncond + (
|
||||
real_score_main_cond - real_score_main_uncond
|
||||
) * args.real_guidance_scale
|
||||
|
||||
# DMD loss
|
||||
fake_to_real_grad = fake_score_main - real_score_main
|
||||
if args.decoupled_dmd:
|
||||
# Decoupled DMD (arXiv:2511.22677, Eq. 8) splits the teacher target into
|
||||
# DM term (shield/regularizer): s_cond(tau_DM) - s_fake(tau_DM), full noise range;
|
||||
# CA term (spear/engine): (alpha - 1) * (s_cond(tau_CA) - s_uncond(tau_CA)), tau_CA > t.
|
||||
# Composing them into one target keeps Eq. 8's (alpha - 1) relative weight under the
|
||||
# single adaptive normalizer of DMD, and reduces exactly to s_cfg when tau_CA == tau_DM.
|
||||
ca_delta = (
|
||||
real_score_ca_cond - real_score_ca_uncond
|
||||
) * (args.real_guidance_scale - 1.0)
|
||||
real_score_target = real_score_main_cond + ca_delta
|
||||
else:
|
||||
real_score_target = real_score_main
|
||||
ca_delta = (
|
||||
real_score_main_cond - real_score_main_uncond
|
||||
) * (args.real_guidance_scale - 1.0)
|
||||
|
||||
# Magnitudes of the two Eq. 6 terms, recomputed from the frozen score tensors so the
|
||||
# monitor costs no extra forward pass and never touches the graph.
|
||||
ca_scale = ca_delta.float().abs().mean()
|
||||
dm_scale = (real_score_main_cond - fake_score_main).float().abs().mean()
|
||||
|
||||
fake_to_real_grad = fake_score_main - real_score_target
|
||||
if dfd_active:
|
||||
normalizer = 1.0 / ((generator_pred.float() - real_score_main.float()).abs().mean(dim=[1, 2, 3, 4], keepdim=True) + 1e-6)
|
||||
normalizer = 1.0 / ((generator_pred.float() - real_score_target.float()).abs().mean(dim=[1, 2, 3, 4], keepdim=True) + 1e-6)
|
||||
fake_to_real_grad = fake_to_real_grad * normalizer.to(fake_to_real_grad.dtype)
|
||||
|
||||
dmd_loss = 0.5 * F.mse_loss(
|
||||
@@ -2344,7 +2489,7 @@ def main():
|
||||
reduction="mean"
|
||||
)
|
||||
else:
|
||||
generator_to_real_norm = generator_pred - real_score_main
|
||||
generator_to_real_norm = generator_pred - real_score_target
|
||||
normalizer = torch.abs(generator_to_real_norm).mean(dim=[1, 2, 3, 4], keepdim=True)
|
||||
fake_to_real_grad = fake_to_real_grad / normalizer
|
||||
fake_to_real_grad = torch.nan_to_num(fake_to_real_grad)
|
||||
@@ -2355,7 +2500,15 @@ def main():
|
||||
reduction="mean"
|
||||
)
|
||||
avg_dmd_loss = accelerator.gather(dmd_loss.repeat(args.train_batch_size)).mean()
|
||||
train_dmd_loss += avg_dmd_loss.item() / args.gradient_accumulation_steps
|
||||
train_dmd_loss += avg_dmd_loss.item()
|
||||
train_gen_log_count += 1
|
||||
|
||||
monitor = accelerator.gather(
|
||||
torch.stack([ca_scale, dm_scale, generator_pred.float().std()])[None]
|
||||
).mean(dim=0)
|
||||
train_ca_scale += monitor[0].item()
|
||||
train_dm_scale += monitor[1].item()
|
||||
train_latent_std += monitor[2].item()
|
||||
|
||||
if args.low_vram:
|
||||
real_score_transformer3d = real_score_transformer3d.to("cpu")
|
||||
@@ -2484,7 +2637,12 @@ def main():
|
||||
|
||||
progress_bar.update(1)
|
||||
global_step += 1
|
||||
tracker_logs = {"train_denoising_loss": train_denoising_loss, "train_dmd_loss": train_dmd_loss}
|
||||
gen_log_div = max(train_gen_log_count, 1)
|
||||
tracker_logs = {"train_denoising_loss": train_denoising_loss, "train_dmd_loss": train_dmd_loss / gen_log_div}
|
||||
tracker_logs["train_ca_scale"] = train_ca_scale / gen_log_div
|
||||
tracker_logs["train_dm_scale"] = train_dm_scale / gen_log_div
|
||||
tracker_logs["train_ca_dm_ratio"] = train_ca_scale / (train_dm_scale + 1e-12)
|
||||
tracker_logs["train_latent_std"] = train_latent_std / gen_log_div
|
||||
if args.dfd:
|
||||
tracker_logs["train_dfd_real_replace"] = train_dfd_real_replace
|
||||
dfd_real_replace_now = train_dfd_real_replace
|
||||
@@ -2492,6 +2650,10 @@ def main():
|
||||
train_dmd_loss = 0.0
|
||||
train_denoising_loss = 0.0
|
||||
train_dfd_real_replace = 0.0
|
||||
train_ca_scale = 0.0
|
||||
train_dm_scale = 0.0
|
||||
train_latent_std = 0.0
|
||||
train_gen_log_count = 0
|
||||
|
||||
if global_step % args.checkpointing_steps == 0:
|
||||
if args.use_deepspeed or args.use_fsdp or accelerator.is_main_process:
|
||||
@@ -2549,25 +2711,35 @@ def main():
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
fake_score_save_path = os.path.join(save_path, "fake_score")
|
||||
accelerator.save_state(save_path)
|
||||
accelerator_fake_score_transformer3d.save_state(fake_score_save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
fake_score_save_path = os.path.join(save_path, "fake_score")
|
||||
accelerator.save_state(save_path)
|
||||
accelerator_fake_score_transformer3d.save_state(fake_score_save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
if args.dfd:
|
||||
logs = {"lr": (lr_scheduler if generator_update else fake_score_lr_scheduler).get_last_lr()[0], "denoising_loss": denoising_loss.detach().item()}
|
||||
@@ -2582,19 +2754,25 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -50,7 +50,6 @@ from PIL import Image
|
||||
from torch.utils.data import RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -72,6 +71,7 @@ from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.lora_utils import (convert_peft_lora_to_kohya_lora,
|
||||
create_network, merge_lora,
|
||||
unmerge_lora)
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
@@ -907,6 +907,7 @@ def main():
|
||||
transformer3d = WanTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
# Freeze vae and text_encoder and set transformer3d to trainable
|
||||
@@ -1503,7 +1504,7 @@ def main():
|
||||
return ckpt_file
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1854,39 +1855,49 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
if args.use_peft_lora:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
network_state_dict = get_peft_model_state_dict(accelerator.unwrap_model(transformer3d))
|
||||
save_model(safetensor_save_path, network_state_dict)
|
||||
|
||||
safetensor_kohya_format_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}-compatible_with_comfyui.safetensors")
|
||||
network_state_dict_kohya = convert_peft_lora_to_kohya_lora(network_state_dict)
|
||||
save_model(safetensor_kohya_format_save_path, network_state_dict_kohya)
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1895,19 +1906,25 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
transformer3d,
|
||||
network,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -65,6 +65,7 @@ from videox_fun.models import (AutoencoderKLWan, CLIPModel, WanT5EncoderModel,
|
||||
WanTransformer3DModel)
|
||||
from videox_fun.pipeline import WanI2VPipeline, WanPipeline
|
||||
from videox_fun.utils.lora_utils import create_network, merge_lora
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import get_image_to_video_latent, save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -106,6 +107,7 @@ def log_validation(
|
||||
transformer3d_val = WanTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
transformer3d_val.load_state_dict(accelerator.unwrap_model(transformer3d).state_dict())
|
||||
scheduler = FlowMatchEulerDiscreteScheduler(
|
||||
@@ -115,7 +117,8 @@ def log_validation(
|
||||
if args.vae_gradient_checkpointing:
|
||||
# Get Vae
|
||||
vae = WanTransformer3DModel.from_pretrained(
|
||||
args.pretrained_model_name_or_path, subfolder="vae", revision=args.revision, variant=args.variant
|
||||
args.pretrained_model_name_or_path, subfolder="vae", revision=args.revision, variant=args.variant,
|
||||
low_cpu_mem_usage=True,
|
||||
).to(weight_dtype)
|
||||
|
||||
pipeline = WanPipeline(
|
||||
@@ -881,6 +884,7 @@ def main():
|
||||
transformer3d = WanTransformer3DModel.from_pretrained(
|
||||
os.path.join(args.pretrained_model_name_or_path, config['transformer_additional_kwargs'].get('transformer_subpath', 'transformer')),
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
|
||||
# if args.train_mode != "normal":
|
||||
@@ -1114,7 +1118,7 @@ def main():
|
||||
accelerator.print(f"\nsaving checkpoint: {ckpt_file}")
|
||||
unwrapped_nw.save_weights(ckpt_file, weight_dtype, None)
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1343,55 +1347,65 @@ def main():
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
if not args.save_state:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
if not args.save_state:
|
||||
safetensor_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}.safetensors")
|
||||
save_model(safetensor_save_path, accelerator.unwrap_model(network))
|
||||
logger.info(f"Saved safetensor to {safetensor_save_path}")
|
||||
else:
|
||||
accelerator_save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(accelerator_save_path)
|
||||
logger.info(f"Saved state to {accelerator_save_path}")
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
|
||||
# Validation (distributed)
|
||||
if do_validation and (global_step % args.validation_steps) == 0:
|
||||
if args.validation_prompts is None and args.validation_prompt_path.endswith(".txt"):
|
||||
validation_prompts = []
|
||||
with open(args.validation_prompt_path, "r") as f:
|
||||
for line in f:
|
||||
validation_prompts.append(line.strip())
|
||||
# Do not select randomly to ensure that `args.validation_prompts` is the same for each process.
|
||||
args.validation_prompts = validation_prompts[:args.validation_batch_size]
|
||||
validation_prompts_idx = [(i, p) for i, p in enumerate(args.validation_prompts)]
|
||||
with progress_bar.paused():
|
||||
if args.validation_prompts is None and args.validation_prompt_path.endswith(".txt"):
|
||||
validation_prompts = []
|
||||
with open(args.validation_prompt_path, "r") as f:
|
||||
for line in f:
|
||||
validation_prompts.append(line.strip())
|
||||
# Do not select randomly to ensure that `args.validation_prompts` is the same for each process.
|
||||
args.validation_prompts = validation_prompts[:args.validation_batch_size]
|
||||
validation_prompts_idx = [(i, p) for i, p in enumerate(args.validation_prompts)]
|
||||
|
||||
if hasattr(vae, "enable_cache_in_vae"):
|
||||
vae.enable_cache_in_vae()
|
||||
accelerator.wait_for_everyone()
|
||||
with accelerator.split_between_processes(validation_prompts_idx) as splitted_prompts_idx:
|
||||
validation_loss, validation_reward = log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
network,
|
||||
loss_fn,
|
||||
config,
|
||||
args,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
splitted_prompts_idx
|
||||
)
|
||||
if validation_loss is not None and validation_reward is not None:
|
||||
avg_validation_loss = accelerator.gather(validation_loss).mean()
|
||||
avg_validation_reward = accelerator.gather(validation_reward).mean()
|
||||
accelerator.print(avg_validation_loss, avg_validation_reward)
|
||||
if accelerator.is_main_process:
|
||||
accelerator.log(
|
||||
{"validation_loss": avg_validation_loss, "validation_reward": avg_validation_reward},
|
||||
step=global_step
|
||||
)
|
||||
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
logs = {"step_loss": loss.detach().item(), "step_reward": reward.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1399,5 +1413,11 @@ def main():
|
||||
if global_step >= args.max_train_steps:
|
||||
break
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
|
||||
@@ -46,7 +46,6 @@ from omegaconf import OmegaConf
|
||||
from packaging import version
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -62,9 +61,10 @@ from videox_fun.data import (ASPECT_RATIO_512, ASPECT_RATIO_RANDOM_CROP_512,
|
||||
AspectRatioBatchImageVideoSampler,
|
||||
ImageVideoDataset, RandomSampler,
|
||||
get_closest_ratio)
|
||||
from videox_fun.models import (AutoencoderKLWan, WanT5EncoderModel,
|
||||
WanTransformer3DModel_SelfForcing)
|
||||
from videox_fun.models import (AutoencoderKLWan, WanTransformer3DModel,
|
||||
WanTransformer3DModel_SelfForcing, WanT5EncoderModel)
|
||||
from videox_fun.pipeline import WanSelfForcingPipeline
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -812,7 +812,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = WanTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1232,7 +1233,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1454,21 +1455,31 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1477,17 +1488,23 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -49,7 +49,6 @@ from torch.distributed.fsdp import FullyShardedDataParallel as FSDP
|
||||
from torch.distributed.fsdp import StateDictType
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -65,9 +64,10 @@ from videox_fun.data import (ASPECT_RATIO_512, ASPECT_RATIO_RANDOM_CROP_512,
|
||||
AspectRatioBatchImageVideoSampler,
|
||||
ImageVideoDataset, RandomSampler,
|
||||
get_closest_ratio)
|
||||
from videox_fun.models import (AutoencoderKLWan, WanT5EncoderModel,
|
||||
WanTransformer3DModel_SelfForcing)
|
||||
from videox_fun.models import (AutoencoderKLWan, WanTransformer3DModel,
|
||||
WanTransformer3DModel_SelfForcing, WanT5EncoderModel)
|
||||
from videox_fun.pipeline import WanSelfForcingPipeline
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import save_videos_grid
|
||||
|
||||
if is_wandb_available():
|
||||
@@ -941,7 +941,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = WanTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1399,7 +1400,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1704,21 +1705,31 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
accelerator.save_state(save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
accelerator.save_state(save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
logs = {"loss": loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -1727,17 +1738,23 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
with progress_bar.paused():
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@@ -56,7 +56,6 @@ from torch.distributed.fsdp.fully_sharded_data_parallel import (
|
||||
from torch.utils.data import BatchSampler, Dataset, RandomSampler
|
||||
from torch.utils.tensorboard import SummaryWriter
|
||||
from torchvision import transforms
|
||||
from tqdm.auto import tqdm
|
||||
from transformers import AutoTokenizer
|
||||
from transformers.utils import ContextManagers
|
||||
|
||||
@@ -79,6 +78,7 @@ from videox_fun.models import (AutoencoderKLWan, CLIPModel, WanT5EncoderModel,
|
||||
from videox_fun.pipeline import (WanI2VPipeline, WanPipeline,
|
||||
WanSelfForcingPipeline)
|
||||
from videox_fun.utils.discrete_sampler import DiscreteSampling
|
||||
from videox_fun.utils.tqdm_bar import PauseAwareTqdm
|
||||
from videox_fun.utils.utils import (calculate_dimensions, get_image_latent,
|
||||
get_image_to_video_latent,
|
||||
save_videos_grid)
|
||||
@@ -117,6 +117,47 @@ def initialize_crossattn_cache_for_training(batch_size, text_len, num_layers, nu
|
||||
return crossattn_cache
|
||||
|
||||
|
||||
def reencode_boundary_latent(vae, pred_latents, weight_dtype, score_num_frames=21):
|
||||
"""
|
||||
Re-encode the boundary frame to get a clean latent for the score window.
|
||||
Follows Self-Forcing reference: decode all frames before the score window, take last pixel frame, re-encode.
|
||||
Input: pred_latents [B, C, F, H, W] (all generated latent frames)
|
||||
Output: boundary_latent [B, C, 1, H, W]
|
||||
"""
|
||||
with torch.no_grad():
|
||||
# Decode all frames except the last (score_num_frames - 1) to pixels
|
||||
tail_len = score_num_frames - 1
|
||||
latent_to_decode = pred_latents[:, :, :-tail_len]
|
||||
# VAE expects [B, C, F, H, W], decode returns [B, C, F, H, W] pixels
|
||||
pixels = vae.decode(latent_to_decode.to(vae.dtype)).sample # [B, C, F, H, W]
|
||||
# Take the last frame
|
||||
frame = pixels[:, :, -1:, :, :] # [B, C, 1, H, W]
|
||||
# Re-encode the last frame to get clean boundary latent
|
||||
boundary_latent = vae.encode(frame)[0].sample().to(weight_dtype) # [B, C, 1, H, W]
|
||||
return boundary_latent
|
||||
|
||||
|
||||
def slice_for_score(pred, vae, weight_dtype, score_num_frames=21, independent_first_frame=False):
|
||||
"""
|
||||
Slice the last `score_num_frames` latent frames for score computation.
|
||||
If pred has more than score_num_frames, re-encode boundary frame for clean context.
|
||||
Returns: (pred_for_score, score_num_frames, need_gradient_mask)
|
||||
"""
|
||||
num_frames = pred.shape[2]
|
||||
if num_frames <= score_num_frames:
|
||||
return pred, num_frames, False
|
||||
|
||||
# Re-encode boundary for cleaner score input
|
||||
try:
|
||||
boundary_latent = reencode_boundary_latent(vae, pred, weight_dtype, score_num_frames=score_num_frames)
|
||||
pred_for_score = torch.cat([boundary_latent, pred[:, :, -(score_num_frames - 1):]], dim=2)
|
||||
except Exception:
|
||||
# Fallback: simple slice without boundary re-encoding
|
||||
pred_for_score = pred[:, :, -score_num_frames:]
|
||||
|
||||
return pred_for_score, score_num_frames, True
|
||||
|
||||
|
||||
def filter_kwargs(cls, kwargs):
|
||||
import inspect
|
||||
sig = inspect.signature(cls.__init__)
|
||||
@@ -1073,7 +1114,7 @@ def main():
|
||||
# Create EMA for the generator_transformer3d.
|
||||
if args.use_ema:
|
||||
if zero_stage == 3:
|
||||
raise NotImplementedError("FSDP does not support EMA.")
|
||||
raise NotImplementedError("DeepSpeed Zero-3 does not support EMA.")
|
||||
|
||||
ema_generator_transformer3d = EMAModel(
|
||||
generator_transformer3d.parameters(),
|
||||
@@ -1125,6 +1166,7 @@ def main():
|
||||
load_model = WanTransformer3DModel_SelfForcing.from_pretrained(
|
||||
input_dir, subfolder="transformer_ema",
|
||||
transformer_additional_kwargs=OmegaConf.to_container(config['transformer_additional_kwargs']),
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
load_model = EMAModel(load_model.parameters(), model_cls=WanTransformer3DModel_SelfForcing, model_config=load_model.config)
|
||||
load_model.load_state_dict(ema_kwargs)
|
||||
@@ -1139,7 +1181,8 @@ def main():
|
||||
|
||||
# load diffusers style into model
|
||||
load_model = WanTransformer3DModel.from_pretrained(
|
||||
input_dir, subfolder="transformer"
|
||||
input_dir, subfolder="transformer",
|
||||
low_cpu_mem_usage=True,
|
||||
)
|
||||
model.register_to_config(**load_model.config)
|
||||
|
||||
@@ -1738,7 +1781,7 @@ def main():
|
||||
else:
|
||||
initial_global_step = 0
|
||||
|
||||
progress_bar = tqdm(
|
||||
progress_bar = PauseAwareTqdm(
|
||||
range(0, args.max_train_steps),
|
||||
initial=initial_global_step,
|
||||
desc="Steps",
|
||||
@@ -1810,6 +1853,10 @@ def main():
|
||||
|
||||
for epoch in range(first_epoch, args.num_train_epochs):
|
||||
train_dmd_loss = 0.0
|
||||
# Number of generator backward contributions since the last log flush; the
|
||||
# generator only backprops every gen_update_interval batches, so its metrics
|
||||
# must be averaged by contribution count, not by gradient_accumulation_steps.
|
||||
train_gen_log_count = 0
|
||||
train_denoising_loss = 0.0
|
||||
batch_sampler.sampler.generator = torch.Generator().manual_seed(args.seed + epoch)
|
||||
for step, batch in enumerate(train_dataloader):
|
||||
@@ -2092,7 +2139,17 @@ def main():
|
||||
text_encoder.to('cpu')
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
with accelerator.accumulate(generator_transformer3d):
|
||||
generator_update = step % args.gen_update_interval == 0
|
||||
# Enter the generator's accumulation context only on batches that actually
|
||||
# backprop through the generator. Entering it on every batch would advance
|
||||
# the accumulation counter gen_update_interval times faster than real
|
||||
# generator gradients are produced; whenever gcd(gradient_accumulation_steps,
|
||||
# gen_update_interval) > 1 the sync flag would then never coincide with a
|
||||
# generator-update batch and optimizer.step() would silently never fire.
|
||||
generator_accumulate_ctx = (
|
||||
accelerator.accumulate(generator_transformer3d) if generator_update else contextlib.nullcontext()
|
||||
)
|
||||
with generator_accumulate_ctx:
|
||||
def get_sigmas(timesteps, n_dim=4, dtype=torch.float32):
|
||||
sigmas = noise_scheduler.sigmas.to(device=accelerator.device, dtype=dtype)
|
||||
schedule_timesteps = noise_scheduler.timesteps.to(accelerator.device)
|
||||
@@ -2168,7 +2225,7 @@ def main():
|
||||
|
||||
# --- Main Training Logic ---
|
||||
bsz, channel, num_frames, height, width = target_shape
|
||||
if step % args.gen_update_interval == 0:
|
||||
if generator_update: # generator_update computed before the accumulate ctx above
|
||||
if args.use_kv_cache_training:
|
||||
# Calculate frame_seq_length
|
||||
patch_h, patch_w = accelerator.unwrap_model(generator_transformer3d).config.patch_size[1:]
|
||||
@@ -2608,7 +2665,8 @@ def main():
|
||||
)
|
||||
|
||||
avg_dmd_loss = accelerator.gather(dmd_loss.repeat(args.train_batch_size)).mean()
|
||||
train_dmd_loss += avg_dmd_loss.item() / args.gradient_accumulation_steps
|
||||
train_dmd_loss += avg_dmd_loss.item()
|
||||
train_gen_log_count += 1
|
||||
|
||||
if args.low_vram:
|
||||
real_score_transformer3d = real_score_transformer3d.to("cpu")
|
||||
@@ -2961,8 +3019,9 @@ def main():
|
||||
ema_generator_transformer3d.step(generator_transformer3d.parameters())
|
||||
progress_bar.update(1)
|
||||
global_step += 1
|
||||
accelerator.log({"train_denoising_loss": train_denoising_loss, "train_dmd_loss": train_dmd_loss}, step=global_step)
|
||||
accelerator.log({"train_denoising_loss": train_denoising_loss, "train_dmd_loss": train_dmd_loss / max(train_gen_log_count, 1)}, step=global_step)
|
||||
train_dmd_loss = 0.0
|
||||
train_gen_log_count = 0
|
||||
train_denoising_loss = 0.0
|
||||
|
||||
if global_step % args.checkpointing_steps == 0:
|
||||
@@ -2991,31 +3050,41 @@ def main():
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_path = os.path.join(args.output_dir, f"checkpoint-{global_step}")
|
||||
fake_score_save_path = os.path.join(save_path, "fake_score")
|
||||
accelerator.save_state(save_path)
|
||||
accelerator_fake_score_transformer3d.save_state(fake_score_save_path)
|
||||
# Keep the checkpoint out of the progress bar rate: a minute-long save would
|
||||
# otherwise land in the next step's interval and be shown as a slow step. The
|
||||
# save also stages the whole state in host RAM (safetensors materializes every
|
||||
# tensor as bytes) and leaves the freed blocks in the allocator caches, so the
|
||||
# cache flushes run inside the same window.
|
||||
with progress_bar.paused():
|
||||
fake_score_save_path = os.path.join(save_path, "fake_score")
|
||||
accelerator.save_state(save_path)
|
||||
accelerator_fake_score_transformer3d.save_state(fake_score_save_path)
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
logger.info(f"Saved state to {save_path}")
|
||||
|
||||
if args.validation_prompts is not None and global_step % args.validation_steps == 0:
|
||||
if args.use_ema:
|
||||
# Store the generator parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_generator_transformer3d.store(generator_transformer3d.parameters())
|
||||
ema_generator_transformer3d.copy_to(generator_transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original generator parameters.
|
||||
ema_generator_transformer3d.restore(generator_transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the generator parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_generator_transformer3d.store(generator_transformer3d.parameters())
|
||||
ema_generator_transformer3d.copy_to(generator_transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original generator parameters.
|
||||
ema_generator_transformer3d.restore(generator_transformer3d.parameters())
|
||||
|
||||
logs = {"denoising_loss": denoising_loss.detach().item(), "dmd_loss": dmd_loss.detach().item(), "lr": lr_scheduler.get_last_lr()[0]}
|
||||
progress_bar.set_postfix(**logs)
|
||||
@@ -3024,25 +3093,31 @@ def main():
|
||||
break
|
||||
|
||||
if args.validation_prompts is not None and epoch % args.validation_epochs == 0:
|
||||
if args.use_ema:
|
||||
# Store the generator parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_generator_transformer3d.store(generator_transformer3d.parameters())
|
||||
ema_generator_transformer3d.copy_to(generator_transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original generator parameters.
|
||||
ema_generator_transformer3d.restore(generator_transformer3d.parameters())
|
||||
with progress_bar.paused():
|
||||
if args.use_ema:
|
||||
# Store the generator parameters temporarily and load the EMA parameters to perform inference.
|
||||
ema_generator_transformer3d.store(generator_transformer3d.parameters())
|
||||
ema_generator_transformer3d.copy_to(generator_transformer3d.parameters())
|
||||
log_validation(
|
||||
vae,
|
||||
text_encoder,
|
||||
tokenizer,
|
||||
clip_image_encoder,
|
||||
generator_transformer3d,
|
||||
args,
|
||||
config,
|
||||
accelerator,
|
||||
weight_dtype,
|
||||
global_step,
|
||||
)
|
||||
if args.use_ema:
|
||||
# Switch back to the original generator parameters.
|
||||
ema_generator_transformer3d.restore(generator_transformer3d.parameters())
|
||||
|
||||
# Close the bar before the end-of-run checkpoint: tqdm keeps redrawing a live bar whenever
|
||||
# something else writes to the console. PauseAwareTqdm.close() rebases the closing line onto
|
||||
# the smoothed rate, so the worker warm-up and the first dataloader fetch do not dilute it.
|
||||
progress_bar.close()
|
||||
|
||||
# Create the pipeline using the trained modules and save it.
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user