First Commit
This commit is contained in:
 Fill
@@ -0,0 +1,59 @@
|
||||
import importlib
|
||||
from . import FL_train_core
|
||||
import os
|
||||
|
||||
class FL_KohyaSSAdvConfig:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"xformers": (["enable", "disable"], {"default": "enable"}),
|
||||
"sdpa": (["enable", "disable"], {"default": "disable"}),
|
||||
"fp8_base": (["enable", "disable"], {"default": "disable"}),
|
||||
"mixed_precision": (["no", "fp16", "bf16"], {"default": "fp16"}),
|
||||
"gradient_accumulation_steps": ("INT", {"default": 1}),
|
||||
"gradient_checkpointing": (["enable", "disable"], {"default": "disable"}),
|
||||
"cache_latents": (["enable", "disable"], {"default": "enable"}),
|
||||
"cache_latents_to_disk": (["enable", "disable"], {"default": "enable"}),
|
||||
"network_dim": ("INT", {"default": 16}),
|
||||
"network_alpha": ("INT", {"default": 8}),
|
||||
"network_module": ([
|
||||
"networks.lora",
|
||||
"networks.dylora",
|
||||
"networks.oft",
|
||||
], {"default": "networks.lora"}),
|
||||
"network_train_unet_only": (["enable", "disable"], {"default": "enable"}),
|
||||
"lr_scheduler": ([
|
||||
"linear", "cosine", "cosine_with_restarts", "polynomial",
|
||||
"constant", "constant_with_warmup", "adafactor"
|
||||
], {"default": "cosine"}),
|
||||
"lr_scheduler_num_cycles": ("INT", {"default": 1}),
|
||||
"optimizer_type": ([
|
||||
"AdamW", "AdamW8bit", "PagedAdamW", "PagedAdamW8bit",
|
||||
"PagedAdamW32bit", "Lion8bit", "PagedLion8bit", "Lion",
|
||||
"SGDNesterov", "SGDNesterov8bit", "DAdaptation", "DAdaptAdaGrad",
|
||||
"DAdaptAdam", "DAdaptAdan", "DAdaptAdanIP", "DAdaptLion",
|
||||
"DAdaptSGD", "AdaFactor"
|
||||
], {"default": "AdamW"}),
|
||||
"lr_warmup_steps": ("INT", {"default": 0}),
|
||||
"unet_lr": ("STRING", {"default": ""}),
|
||||
"text_encoder_lr": ("STRING", {"default": ""}),
|
||||
"shuffle_caption": (["enable", "disable"], {"default": "disable"}),
|
||||
"save_precision": (["float", "fp16", "bf16"], {"default": "fp16"}),
|
||||
"persistent_data_loader_workers": (["enable", "disable"], {"default": "enable"}),
|
||||
"no_metadata": (["enable", "disable"], {"default": "enable"}),
|
||||
"noise_offset": ("FLOAT", {"default": 0.1}),
|
||||
"no_half_vae": (["enable", "disable"], {"default": "enable"}),
|
||||
"lowram": (["enable", "disable"], {"default": "disable"}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("FL_TT_SS_AdvConfig",)
|
||||
RETURN_NAMES = ("advanced_config",)
|
||||
|
||||
FUNCTION = "start"
|
||||
CATEGORY = "🏵️Fill Nodes/Training"
|
||||
|
||||
def start(self, **kwargs):
|
||||
importlib.reload(FL_train_core)
|
||||
return FL_train_core.FL_KohyaSSAdvConfig_call(kwargs)
|
||||
@@ -0,0 +1,37 @@
|
||||
import importlib
|
||||
from .FL_train_utils import Utils
|
||||
from . import FL_train_core
|
||||
import os
|
||||
|
||||
class FL_KohyaSSDatasetConfig:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"workspace_config": ("FL_TT_SS_WorkspaceConfig",),
|
||||
"images": ("IMAGE",),
|
||||
"captions": ("STRING", {"forceInput": True}),
|
||||
"enable_bucket": (["enable", "disable"], {"default": "enable"}),
|
||||
"resolution": ("INT", {"default": 1024}),
|
||||
"num_repeats": ("INT", {"default": 1}),
|
||||
"caption_extension": ([".caption", ".txt"], {"default": ".caption"}),
|
||||
"batch_size": ("INT", {"default": 1, "min":1}),
|
||||
"force_clear": (["enable", "disable"], {"default": "disable"}),
|
||||
"force_clear_only_images": (["enable", "disable"], {"default": "disable"}),
|
||||
"image_format": (["png", "jpg", "webp"], {"default": "webp"}),
|
||||
"dataset_config_extension": ([".toml", ".json"], {"default": ".json"}),
|
||||
},
|
||||
"optional": {
|
||||
"conditioning_images": ("IMAGE",),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
RETURN_NAMES = ("workspace_images_dir",)
|
||||
|
||||
FUNCTION = "start"
|
||||
CATEGORY = "🏵️Fill Nodes/Training"
|
||||
|
||||
def start(self, **kwargs):
|
||||
importlib.reload(FL_train_core)
|
||||
return FL_train_core.FL_ImageSelecter_call(kwargs)
|
||||
@@ -0,0 +1,31 @@
|
||||
import importlib
|
||||
from .FL_train_utils import Utils
|
||||
from . import FL_train_core
|
||||
import os
|
||||
|
||||
class FL_KohyaSSInitWorkspace:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"lora_name": ("STRING", {"default": ""}),
|
||||
"branch": ("STRING", {"default": "71e2c91330a9d866ec05cdd10584bbb962896a99"}),
|
||||
"source": ([
|
||||
"github",
|
||||
"githubfast",
|
||||
"521github",
|
||||
"kkgithub",
|
||||
], {"default": "github"}),
|
||||
"seed": ("INT", {"default": 0}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("FL_TT_SS_WorkspaceConfig",)
|
||||
RETURN_NAMES = ("workspace_config",)
|
||||
|
||||
FUNCTION = "start"
|
||||
CATEGORY = "🏵️Fill Nodes/Training"
|
||||
|
||||
def start(self, **kwargs):
|
||||
importlib.reload(FL_train_core)
|
||||
return FL_train_core.FL_KohyaSSInitWorkspace_call(kwargs)
|
||||
@@ -0,0 +1,93 @@
|
||||
import os
|
||||
import importlib
|
||||
import folder_paths
|
||||
from .FL_train_utils import AlwaysEqualProxy, Utils
|
||||
|
||||
class FL_KohyaSSTrain:
|
||||
train_config_template_dir = os.path.join(
|
||||
os.path.dirname(__file__), "configs", "kohya_ss_lora"
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
loras = [
|
||||
"latest",
|
||||
"empty",
|
||||
]
|
||||
|
||||
workspaces_dir = os.path.join(
|
||||
folder_paths.output_directory, "FL_train_workspaces")
|
||||
|
||||
workspaces_loras = []
|
||||
for root, dirs, files in os.walk(workspaces_dir):
|
||||
dirs[:] = [d for d in dirs if not d.startswith(".")]
|
||||
if root.endswith("output"):
|
||||
for file in files:
|
||||
if file.endswith(".safetensors"):
|
||||
workspaces_loras.append(
|
||||
os.path.join(root, file)
|
||||
)
|
||||
|
||||
workspaces_loras = sorted(
|
||||
workspaces_loras, key=lambda x: os.path.getctime(x), reverse=True)
|
||||
|
||||
comfyui_full_loras = []
|
||||
comfyui_loras = folder_paths.get_filename_list("loras")
|
||||
for lora in comfyui_loras:
|
||||
lora_path = folder_paths.get_full_path("loras", lora)
|
||||
comfyui_full_loras.append(lora_path)
|
||||
|
||||
comfyui_full_loras = sorted(
|
||||
comfyui_full_loras, key=lambda x: os.path.getctime(x), reverse=True)
|
||||
|
||||
loras = loras + workspaces_loras + comfyui_full_loras
|
||||
|
||||
train_config_templates = Utils.listdir(s.train_config_template_dir)
|
||||
|
||||
priority = [
|
||||
"lora",
|
||||
"1_2",
|
||||
"1_1"
|
||||
]
|
||||
|
||||
train_config_templates = [os.path.splitext(x)[0]
|
||||
for x in train_config_templates]
|
||||
|
||||
def priority_sort(x):
|
||||
for p in priority:
|
||||
if x.find(p) != -1:
|
||||
return priority.index(p)
|
||||
return 999
|
||||
|
||||
train_config_templates = sorted(
|
||||
train_config_templates, key=priority_sort)
|
||||
|
||||
return {
|
||||
"required": {
|
||||
"workspace_config": ("FL_TT_SS_WorkspaceConfig",),
|
||||
"train_config_template": (train_config_templates,),
|
||||
"ckpt_name": (folder_paths.get_filename_list("checkpoints"), ),
|
||||
"max_train_steps": ("INT", {"default": 0, "min": 0, "max": 0x7fffffff}),
|
||||
"max_train_epochs": ("INT", {"default": 100, "min": 0, "max": 0x7fffffff}),
|
||||
"save_every_n_epochs": ("INT", {"default": 10}),
|
||||
"learning_rate": ("STRING", {"default": "1e-5"}),
|
||||
"base_lora": (loras, {"default": "latest"}),
|
||||
"sample_generate": (["enable", "disable"], {"default": "enable"}),
|
||||
"sample_prompt": ("STRING", {"default": "", "dynamicPrompts": False, "multiline": False}),
|
||||
},
|
||||
"optional": {
|
||||
"advanced_config": ("FL_TT_SS_AdvConfig",),
|
||||
"caption_completed_flag": (AlwaysEqualProxy("*"),),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ()
|
||||
RETURN_NAMES = ()
|
||||
OUTPUT_NODE = True
|
||||
FUNCTION = "start"
|
||||
CATEGORY = "🏵️Fill Nodes/Training"
|
||||
|
||||
def start(self, **kwargs):
|
||||
from . import FL_train_core
|
||||
importlib.reload(FL_train_core)
|
||||
return FL_train_core.FL_KohyaSSTrain_call(kwargs)
|
||||
@@ -0,0 +1,42 @@
|
||||
from .FL_train_utils import Utils
|
||||
import os
|
||||
from PIL import Image
|
||||
|
||||
class FL_LoadImagesFromDirectoryPath:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"directory": ("STRING", {"default": "X://path/to/images"}),
|
||||
"caption_extension": ([".caption", ".txt"], {"default": ".caption"}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE", "STRING")
|
||||
RETURN_NAMES = ("images", "captions")
|
||||
|
||||
FUNCTION = "start"
|
||||
|
||||
CATEGORY = "🏵️Fill Nodes/Training"
|
||||
|
||||
def start(self, directory, caption_extension):
|
||||
|
||||
images = []
|
||||
captions = []
|
||||
if not os.path.exists(directory):
|
||||
return (Utils.list_tensor2tensor([]), [])
|
||||
|
||||
files = Utils.listdir(directory)
|
||||
image_files = [f for f in files if f.lower().endswith((".png", ".jpg", ".webp", ".jpeg"))]
|
||||
|
||||
for image_file in image_files:
|
||||
image_path = os.path.join(directory, image_file)
|
||||
caption_path = os.path.splitext(image_path)[0] + caption_extension
|
||||
|
||||
if os.path.exists(caption_path):
|
||||
with open(caption_path, 'r', encoding='utf-8') as f:
|
||||
captions.append(f.read().strip())
|
||||
pil_image = Image.open(image_path)
|
||||
images.append(Utils.pil2tensor(pil_image))
|
||||
|
||||
return (Utils.list_tensor2tensor(images), captions)
|
||||
+1022
File diff suppressed because it is too large
Load Diff
+1227
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,56 @@
|
||||
class FL_SliderLoraAdvConfig:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"learning_rate": ("FLOAT", {"default": 1e-4, "min": 1e-6, "max": 1e-2, "step": 1e-6}),
|
||||
"num_train_epochs": ("INT", {"default": 50, "min": 1, "max": 1000}),
|
||||
"max_train_steps": ("INT", {"default": 10000, "min": 100, "max": 1000000}),
|
||||
"gradient_accumulation_steps": ("INT", {"default": 1, "min": 1, "max": 64}),
|
||||
"lr_scheduler": (["constant", "linear", "cosine", "cosine_with_restarts"], {"default": "constant"}),
|
||||
"lr_warmup_steps": ("INT", {"default": 0, "min": 0, "max": 10000}),
|
||||
"adam_beta1": ("FLOAT", {"default": 0.9, "min": 0.0, "max": 1.0, "step": 0.01}),
|
||||
"adam_beta2": ("FLOAT", {"default": 0.999, "min": 0.0, "max": 1.0, "step": 0.001}),
|
||||
"adam_weight_decay": ("FLOAT", {"default": 1e-2, "min": 0.0, "max": 1.0, "step": 1e-3}),
|
||||
"adam_epsilon": ("FLOAT", {"default": 1e-8, "min": 1e-10, "max": 1e-6, "step": 1e-10}),
|
||||
"max_grad_norm": ("FLOAT", {"default": 1.0, "min": 0.0, "max": 10.0, "step": 0.1}),
|
||||
},
|
||||
"optional": {
|
||||
"train_text_encoder": ("BOOLEAN", {"default": False}),
|
||||
"predenoise_num_train_timesteps": ("INT", {"default": 50, "min": 1, "max": 1000}),
|
||||
"noise_offset": ("FLOAT", {"default": 0.0, "min": 0.0, "max": 1.0, "step": 0.01}),
|
||||
"use_8bit_adam": ("BOOLEAN", {"default": False}),
|
||||
"gradient_checkpointing": ("BOOLEAN", {"default": False}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("FL_SLIDER_LORA_ADV_CONFIG",)
|
||||
RETURN_NAMES = ("advanced_config",)
|
||||
|
||||
FUNCTION = "create_advanced_config"
|
||||
CATEGORY = "FL_Slider_Lora"
|
||||
|
||||
def create_advanced_config(self, learning_rate, num_train_epochs, max_train_steps, gradient_accumulation_steps,
|
||||
lr_scheduler, lr_warmup_steps, adam_beta1, adam_beta2, adam_weight_decay, adam_epsilon,
|
||||
max_grad_norm, train_text_encoder=False, predenoise_num_train_timesteps=50,
|
||||
noise_offset=0.0, use_8bit_adam=False, gradient_checkpointing=False):
|
||||
advanced_config = {
|
||||
"learning_rate": learning_rate,
|
||||
"num_train_epochs": num_train_epochs,
|
||||
"max_train_steps": max_train_steps,
|
||||
"gradient_accumulation_steps": gradient_accumulation_steps,
|
||||
"lr_scheduler": lr_scheduler,
|
||||
"lr_warmup_steps": lr_warmup_steps,
|
||||
"adam_beta1": adam_beta1,
|
||||
"adam_beta2": adam_beta2,
|
||||
"adam_weight_decay": adam_weight_decay,
|
||||
"adam_epsilon": adam_epsilon,
|
||||
"max_grad_norm": max_grad_norm,
|
||||
"train_text_encoder": train_text_encoder,
|
||||
"predenoise_num_train_timesteps": predenoise_num_train_timesteps,
|
||||
"noise_offset": noise_offset,
|
||||
"use_8bit_adam": use_8bit_adam,
|
||||
"gradient_checkpointing": gradient_checkpointing,
|
||||
}
|
||||
|
||||
return (advanced_config,)
|
||||
@@ -0,0 +1,127 @@
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from typing import List, Union, Optional, Tuple
|
||||
from diffusers import DDPMScheduler, UNet2DConditionModel
|
||||
from transformers import CLIPTextModel, CLIPTokenizer
|
||||
|
||||
|
||||
class SliderLoraPipelineBase:
|
||||
def __init__(
|
||||
self,
|
||||
unet: UNet2DConditionModel,
|
||||
text_encoder: Union[CLIPTextModel, List[CLIPTextModel]],
|
||||
tokenizer: Union[CLIPTokenizer, List[CLIPTokenizer]],
|
||||
scheduler: DDPMScheduler,
|
||||
vae=None,
|
||||
):
|
||||
self.unet = unet
|
||||
self.text_encoder = text_encoder
|
||||
self.tokenizer = tokenizer
|
||||
self.scheduler = scheduler
|
||||
self.vae = vae
|
||||
|
||||
def encode_prompt(self, prompt: str) -> torch.Tensor:
|
||||
raise NotImplementedError("Subclasses must implement this method")
|
||||
|
||||
def pre_denoise(
|
||||
self,
|
||||
latents: torch.Tensor,
|
||||
prompt_embeds: torch.Tensor,
|
||||
timesteps: int,
|
||||
guidance_scale: float,
|
||||
) -> torch.Tensor:
|
||||
for i, t in enumerate(self.scheduler.timesteps[:timesteps]):
|
||||
latent_model_input = torch.cat([latents] * 2)
|
||||
latent_model_input = self.scheduler.scale_model_input(latent_model_input, timestep=t)
|
||||
|
||||
# Predict the noise residual
|
||||
with torch.no_grad():
|
||||
noise_pred = self.unet(
|
||||
latent_model_input,
|
||||
t,
|
||||
encoder_hidden_states=prompt_embeds
|
||||
).sample
|
||||
|
||||
# Perform guidance
|
||||
noise_pred_uncond, noise_pred_text = noise_pred.chunk(2)
|
||||
noise_pred = noise_pred_uncond + guidance_scale * (noise_pred_text - noise_pred_uncond)
|
||||
|
||||
# Compute the previous noisy sample x_t -> x_t-1
|
||||
latents = self.scheduler.step(noise_pred, t, latents).prev_sample
|
||||
|
||||
return latents
|
||||
|
||||
def predict_noise(
|
||||
self,
|
||||
latents: torch.Tensor,
|
||||
prompt_embeds: torch.Tensor,
|
||||
timestep: int,
|
||||
guidance_scales: List[float],
|
||||
) -> torch.Tensor:
|
||||
latent_model_input = torch.cat([latents] * len(guidance_scales))
|
||||
|
||||
# Predict the noise residual
|
||||
noise_pred = self.unet(
|
||||
latent_model_input,
|
||||
timestep,
|
||||
encoder_hidden_states=prompt_embeds
|
||||
).sample
|
||||
|
||||
# Perform guidance
|
||||
noise_pred_chunks = noise_pred.chunk(len(guidance_scales))
|
||||
noise_pred = torch.stack([n * g for n, g in zip(noise_pred_chunks, guidance_scales)]).sum(dim=0)
|
||||
|
||||
return noise_pred
|
||||
|
||||
|
||||
def combine_tensors(tensors: List[torch.Tensor], repeats: int) -> torch.Tensor:
|
||||
return torch.cat(tensors).repeat_interleave(repeats, dim=0)
|
||||
|
||||
|
||||
def get_timesteps(scheduler: DDPMScheduler, num_inference_steps: int, strength: float, device):
|
||||
# Get the original timestep using init_timestep
|
||||
init_timestep = min(int(num_inference_steps * strength), num_inference_steps)
|
||||
|
||||
t_start = max(num_inference_steps - init_timestep, 0)
|
||||
timesteps = scheduler.timesteps[t_start:]
|
||||
|
||||
return timesteps, num_inference_steps - t_start
|
||||
|
||||
|
||||
class SliderLoraSD15Pipeline(SliderLoraPipelineBase):
|
||||
def encode_prompt(self, prompt: str) -> torch.Tensor:
|
||||
text_input = self.tokenizer(
|
||||
prompt,
|
||||
padding="max_length",
|
||||
max_length=self.tokenizer.model_max_length,
|
||||
truncation=True,
|
||||
return_tensors="pt",
|
||||
)
|
||||
return self.text_encoder(text_input.input_ids.to(self.text_encoder.device))[0]
|
||||
|
||||
|
||||
class SliderLoraSDXLPipeline(SliderLoraPipelineBase):
|
||||
def encode_prompt(self, prompt: str) -> Tuple[torch.Tensor, torch.Tensor]:
|
||||
prompt_embeds_list = []
|
||||
pooled_prompt_embeds = None
|
||||
|
||||
for i, text_encoder in enumerate(self.text_encoder):
|
||||
text_input = self.tokenizer[i](
|
||||
prompt,
|
||||
padding="max_length",
|
||||
max_length=self.tokenizer[i].model_max_length,
|
||||
truncation=True,
|
||||
return_tensors="pt",
|
||||
)
|
||||
prompt_embeds = text_encoder(
|
||||
text_input.input_ids.to(text_encoder.device),
|
||||
output_hidden_states=True,
|
||||
)
|
||||
pooled_prompt_embeds = prompt_embeds[0]
|
||||
prompt_embeds = prompt_embeds.hidden_states[-2]
|
||||
prompt_embeds_list.append(prompt_embeds)
|
||||
|
||||
prompt_embeds = torch.cat(prompt_embeds_list, dim=-1)
|
||||
return prompt_embeds, pooled_prompt_embeds
|
||||
|
||||
# Additional utility functions can be added here as needed
|
||||
@@ -0,0 +1,45 @@
|
||||
class FL_SliderLoraDatasetConfig:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"workspace": ("FL_SLIDER_LORA_WORKSPACE",),
|
||||
"target_prompt_1": ("STRING", {"default": ""}),
|
||||
"trigger_prompt_1": ("STRING", {"default": "style"}),
|
||||
"trigger_lora_weight_1": (["positive", "negative"], {"default": "positive"}),
|
||||
"guidance_scale_1": ("FLOAT", {"default": 7.0, "min": 0.1, "max": 30.0, "step": 0.1}),
|
||||
},
|
||||
"optional": {
|
||||
"target_prompt_2": ("STRING", {"default": ""}),
|
||||
"trigger_prompt_2": ("STRING", {"default": "style"}),
|
||||
"trigger_lora_weight_2": (["positive", "negative"], {"default": "negative"}),
|
||||
"guidance_scale_2": ("FLOAT", {"default": 7.0, "min": 0.1, "max": 30.0, "step": 0.1}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("FL_SLIDER_LORA_DATASET",)
|
||||
RETURN_NAMES = ("dataset",)
|
||||
|
||||
FUNCTION = "prepare_dataset"
|
||||
CATEGORY = "FL_Slider_Lora"
|
||||
|
||||
def prepare_dataset(self, workspace, target_prompt_1, trigger_prompt_1, trigger_lora_weight_1, guidance_scale_1,
|
||||
target_prompt_2="", trigger_prompt_2="", trigger_lora_weight_2="", guidance_scale_2=0.0):
|
||||
dataset = [
|
||||
{
|
||||
"target_prompt": target_prompt_1,
|
||||
"trigger_prompt": trigger_prompt_1,
|
||||
"trigger_lora_weight": 1 if trigger_lora_weight_1 == "positive" else -1,
|
||||
"guidance_scale": guidance_scale_1
|
||||
}
|
||||
]
|
||||
|
||||
if target_prompt_2 and trigger_prompt_2 and trigger_lora_weight_2 and guidance_scale_2 > 0:
|
||||
dataset.append({
|
||||
"target_prompt": target_prompt_2,
|
||||
"trigger_prompt": trigger_prompt_2,
|
||||
"trigger_lora_weight": 1 if trigger_lora_weight_2 == "positive" else -1,
|
||||
"guidance_scale": guidance_scale_2
|
||||
})
|
||||
|
||||
return (dataset,)
|
||||
@@ -0,0 +1,232 @@
|
||||
import os
|
||||
import torch
|
||||
import json
|
||||
from safetensors import safe_open
|
||||
from diffusers import AutoencoderKL, UNet2DConditionModel, DDPMScheduler
|
||||
from diffusers.models.embeddings import TimestepEmbedding, Timesteps
|
||||
from transformers import CLIPTextModel, CLIPTokenizer, CLIPConfig
|
||||
from .FL_SliderLoraCore import SliderLoraSD15Pipeline, SliderLoraSDXLPipeline
|
||||
import folder_paths
|
||||
import diffusers
|
||||
from .FL_train_utils import Utils
|
||||
|
||||
|
||||
class CustomAutoencoder(AutoencoderKL):
|
||||
def __init__(self, *args, **kwargs):
|
||||
super().__init__(*args, **kwargs)
|
||||
self.encoder.down_blocks = torch.nn.ModuleList([
|
||||
torch.nn.ModuleDict({"block": torch.nn.ModuleList([]), "downsample": None})
|
||||
for _ in range(4)
|
||||
])
|
||||
self.decoder.up_blocks = torch.nn.ModuleList([
|
||||
torch.nn.ModuleDict({"block": torch.nn.ModuleList([]), "upsample": None})
|
||||
for _ in range(4)
|
||||
])
|
||||
self.encoder.mid = torch.nn.Module()
|
||||
self.decoder.mid = torch.nn.Module()
|
||||
|
||||
|
||||
class FL_SliderLoraInitWorkspace:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"model_name": (folder_paths.get_filename_list("checkpoints"),),
|
||||
"model_type": (["SD1.5", "SDXL"],),
|
||||
"lora_name": ("STRING", {"default": ""}),
|
||||
"resolution": ("INT", {"default": 512, "min": 256, "max": 2048, "step": 64}),
|
||||
"rank": ("INT", {"default": 4, "min": 1, "max": 128, "step": 1}),
|
||||
"device": (["cuda", "cpu"],),
|
||||
"seed": ("INT", {"default": 0}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("FL_SLIDER_LORA_WORKSPACE",)
|
||||
RETURN_NAMES = ("workspace",)
|
||||
|
||||
FUNCTION = "init_workspace"
|
||||
CATEGORY = "FL_Slider_Lora"
|
||||
|
||||
def init_workspace(self, model_name, model_type, lora_name, resolution, rank, device, seed):
|
||||
model_path = folder_paths.get_full_path("checkpoints", model_name)
|
||||
|
||||
vae, unet, scheduler, text_encoder, tokenizer = self.load_model_components(model_path, model_type, device)
|
||||
|
||||
# Set up LoRA config
|
||||
from peft import LoraConfig
|
||||
lora_config = LoraConfig(
|
||||
r=rank,
|
||||
lora_alpha=rank,
|
||||
target_modules=["q_proj", "v_proj"],
|
||||
lora_dropout=0.1,
|
||||
bias="none",
|
||||
)
|
||||
|
||||
# Create workspace directory
|
||||
workspace_dir = os.path.join(folder_paths.get_output_directory(), "slider_lora_workspaces", lora_name)
|
||||
os.makedirs(workspace_dir, exist_ok=True)
|
||||
|
||||
# Set random seed
|
||||
torch.manual_seed(seed)
|
||||
if device == "cuda":
|
||||
torch.cuda.manual_seed_all(seed)
|
||||
|
||||
# Create pipeline
|
||||
pipeline = self.create_pipeline(model_type, unet, text_encoder, tokenizer, scheduler, vae)
|
||||
|
||||
workspace = {
|
||||
"pipeline": pipeline,
|
||||
"lora_config": lora_config,
|
||||
"workspace_dir": workspace_dir,
|
||||
"model_type": model_type,
|
||||
"resolution": resolution,
|
||||
"device": device,
|
||||
}
|
||||
|
||||
return (workspace,)
|
||||
|
||||
def load_model_components(self, model_path, model_type, device):
|
||||
print(f"Diffusers version: {diffusers.__version__}")
|
||||
|
||||
config_path = os.path.join(os.path.dirname(__file__), "configs", "models_config")
|
||||
|
||||
if model_type == "SD1.5":
|
||||
config_path = os.path.join(config_path, "stable-diffusion-v1-5")
|
||||
elif model_type == "SDXL":
|
||||
config_path = os.path.join(config_path, "stable-diffusion-xl-base-1.0")
|
||||
else:
|
||||
raise ValueError(f"Unsupported model type: {model_type}")
|
||||
|
||||
if model_path.endswith('.safetensors'):
|
||||
print(f"Loading .safetensors model: {model_path}")
|
||||
state_dict = self.load_safetensors(model_path)
|
||||
|
||||
# Load configs
|
||||
with open(os.path.join(config_path, "unet", "config.json"), "r") as f:
|
||||
unet_config = json.load(f)
|
||||
|
||||
print("UNet config:")
|
||||
for key, value in unet_config.items():
|
||||
print(f" {key}: {value}")
|
||||
|
||||
print("Creating custom UNet...")
|
||||
print("UNet config keys:", unet_config.keys())
|
||||
print("UNet block_out_channels:", unet_config.get('block_out_channels'))
|
||||
print("UNet time_embed_dim:", unet_config.get('time_embed_dim'))
|
||||
|
||||
with open(os.path.join(config_path, "text_encoder", "config.json"), "r") as f:
|
||||
text_encoder_config = json.load(f)
|
||||
with open(os.path.join(config_path, "vae", "config.json"), "r") as f:
|
||||
vae_config = json.load(f)
|
||||
|
||||
# Initialize models with configs
|
||||
unet = self.create_custom_unet(unet_config)
|
||||
print("Custom UNet created successfully.")
|
||||
|
||||
text_encoder = CLIPTextModel(config=CLIPConfig(**text_encoder_config))
|
||||
vae = CustomAutoencoder(**vae_config)
|
||||
|
||||
# Load state dicts
|
||||
unet_state_dict = self.filter_state_dict(state_dict, "model.diffusion_model.")
|
||||
unet.load_state_dict(unet_state_dict, strict=False)
|
||||
|
||||
text_encoder_state_dict = self.filter_state_dict(state_dict, "cond_stage_model.transformer.")
|
||||
text_encoder_state_dict = {k: v for k, v in text_encoder_state_dict.items() if
|
||||
k in text_encoder.state_dict()}
|
||||
text_encoder.load_state_dict(text_encoder_state_dict, strict=False)
|
||||
|
||||
vae_state_dict = self.filter_state_dict(state_dict, "first_stage_model.")
|
||||
vae_state_dict = self.adapt_vae_state_dict(vae_state_dict)
|
||||
vae.load_state_dict(vae_state_dict, strict=False)
|
||||
|
||||
# Move models to device
|
||||
unet = unet.to(device)
|
||||
text_encoder = text_encoder.to(device)
|
||||
vae = vae.to(device)
|
||||
|
||||
# Initialize scheduler and tokenizer
|
||||
scheduler = DDPMScheduler.from_pretrained(os.path.join(config_path, "scheduler"))
|
||||
tokenizer = CLIPTokenizer.from_pretrained(os.path.join(config_path, "tokenizer"))
|
||||
else:
|
||||
print(f"Loading model from directory: {model_path}")
|
||||
vae = AutoencoderKL.from_pretrained(model_path, subfolder="vae").to(device)
|
||||
unet = UNet2DConditionModel.from_pretrained(model_path, subfolder="unet").to(device)
|
||||
scheduler = DDPMScheduler.from_pretrained(model_path, subfolder="scheduler")
|
||||
text_encoder = CLIPTextModel.from_pretrained(model_path, subfolder="text_encoder").to(device)
|
||||
tokenizer = CLIPTokenizer.from_pretrained(model_path, subfolder="tokenizer")
|
||||
|
||||
return vae, unet, scheduler, text_encoder, tokenizer
|
||||
|
||||
def load_safetensors(self, path):
|
||||
with safe_open(path, framework="pt", device="cpu") as f:
|
||||
return {key: f.get_tensor(key) for key in f.keys()}
|
||||
|
||||
def filter_state_dict(self, state_dict, prefix):
|
||||
return {k.replace(prefix, ""): v for k, v in state_dict.items() if k.startswith(prefix)}
|
||||
|
||||
def create_custom_unet(self, config):
|
||||
original_unet = UNet2DConditionModel(**config)
|
||||
|
||||
class CustomUNetWrapper(torch.nn.Module):
|
||||
def __init__(self, unet):
|
||||
super().__init__()
|
||||
self.unet = unet
|
||||
self.config = unet.config
|
||||
# Copy any other necessary attributes from the original UNet
|
||||
for attr_name in dir(unet):
|
||||
if not attr_name.startswith('_') and not hasattr(self, attr_name):
|
||||
setattr(self, attr_name, getattr(unet, attr_name))
|
||||
|
||||
def forward(self, sample, timestep, encoder_hidden_states, class_labels=None, return_dict=True):
|
||||
# Ensure timestep is a 1D tensor
|
||||
if not torch.is_tensor(timestep):
|
||||
timestep = torch.tensor([timestep], dtype=torch.long, device=sample.device)
|
||||
timestep = timestep.to(sample.device).view(-1)
|
||||
|
||||
# If timestep is a single value, repeat it to match the batch size
|
||||
if timestep.shape[0] == 1:
|
||||
timestep = timestep.repeat(sample.shape[0])
|
||||
|
||||
print(f"Debug - CustomUNetWrapper - sample shape: {sample.shape}")
|
||||
print(f"Debug - CustomUNetWrapper - timestep shape: {timestep.shape}")
|
||||
print(f"Debug - CustomUNetWrapper - timestep value: {timestep}")
|
||||
|
||||
# Call the original UNet's forward method
|
||||
return self.unet(sample, timestep, encoder_hidden_states, class_labels, return_dict)
|
||||
|
||||
return CustomUNetWrapper(original_unet)
|
||||
|
||||
def adapt_vae_state_dict(self, state_dict):
|
||||
new_state_dict = {}
|
||||
for k, v in state_dict.items():
|
||||
if k.startswith('encoder.') or k.startswith('decoder.'):
|
||||
parts = k.split('.')
|
||||
if parts[1] in ['down', 'up']:
|
||||
block_idx = int(parts[2])
|
||||
new_key = f"{parts[0]}.{'down' if parts[1] == 'down' else 'up'}_blocks.{block_idx}"
|
||||
if parts[3] == 'block':
|
||||
new_key += f".resnets.{parts[4]}"
|
||||
elif parts[3] in ['upsample', 'downsample']:
|
||||
new_key += f".{parts[3]}rs.0"
|
||||
new_key += '.'.join(parts[5:])
|
||||
elif parts[1] == 'mid':
|
||||
new_key = f"{parts[0]}.mid_block"
|
||||
if parts[2] == 'block':
|
||||
new_key += f".resnets.{int(parts[3]) - 1}"
|
||||
elif parts[2] == 'attn':
|
||||
new_key += ".attentions.0"
|
||||
new_key += '.'.join(parts[4:])
|
||||
else:
|
||||
new_key = k
|
||||
else:
|
||||
new_key = k
|
||||
new_state_dict[new_key] = v
|
||||
return new_state_dict
|
||||
|
||||
def create_pipeline(self, model_type, unet, text_encoder, tokenizer, scheduler, vae):
|
||||
if model_type == "SD1.5":
|
||||
return SliderLoraSD15Pipeline(unet, text_encoder, tokenizer, scheduler, vae)
|
||||
elif model_type == "SDXL":
|
||||
return SliderLoraSDXLPipeline(unet, text_encoder, tokenizer, scheduler, vae)
|
||||
else:
|
||||
raise ValueError(f"Unsupported model type: {model_type}")
|
||||
@@ -0,0 +1,260 @@
|
||||
import os
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from torch.utils.data import DataLoader
|
||||
from torch.utils.checkpoint import checkpoint
|
||||
from accelerate import Accelerator
|
||||
from diffusers.optimization import get_scheduler
|
||||
from tqdm.auto import tqdm
|
||||
from peft import get_peft_model_state_dict
|
||||
import safetensors.torch
|
||||
from PIL import Image
|
||||
import folder_paths
|
||||
from .FL_train_utils import Utils
|
||||
|
||||
class GradientEnabledModule(torch.nn.Module):
|
||||
def __init__(self, module):
|
||||
super().__init__()
|
||||
self.module = module
|
||||
self.module.train() # Ensure the module is in training mode
|
||||
|
||||
def forward(self, *args, **kwargs):
|
||||
with torch.enable_grad():
|
||||
return self.module(*args, **kwargs)
|
||||
|
||||
class FL_SliderLoraTrain:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"workspace": ("FL_SLIDER_LORA_WORKSPACE",),
|
||||
"dataset": ("FL_SLIDER_LORA_DATASET",),
|
||||
"advanced_config": ("FL_SLIDER_LORA_ADV_CONFIG",),
|
||||
"save_every_n_steps": ("INT", {"default": 500, "min": 100, "max": 10000, "step": 100}),
|
||||
"num_checkpoint_limit": ("INT", {"default": 5, "min": 1, "max": 20}),
|
||||
"generate_every_n_steps": ("INT", {"default": 1000, "min": 100, "max": 10000, "step": 100}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ()
|
||||
FUNCTION = "train"
|
||||
CATEGORY = "FL_Slider_Lora"
|
||||
OUTPUT_NODE = True
|
||||
|
||||
def train(self, workspace, dataset, advanced_config, save_every_n_steps, num_checkpoint_limit,
|
||||
generate_every_n_steps):
|
||||
# Set up accelerator
|
||||
accelerator = Accelerator(
|
||||
gradient_accumulation_steps=advanced_config["gradient_accumulation_steps"],
|
||||
mixed_precision="fp16" if workspace["device"] == "cuda" else "no"
|
||||
)
|
||||
|
||||
# Prepare model components
|
||||
unet = workspace["pipeline"].unet
|
||||
text_encoder = workspace["pipeline"].text_encoder
|
||||
vae = workspace["pipeline"].vae
|
||||
tokenizer = workspace["pipeline"].tokenizer
|
||||
scheduler = workspace["pipeline"].scheduler
|
||||
|
||||
# Explicitly set models to train/eval mode
|
||||
unet.train()
|
||||
vae.eval()
|
||||
text_encoder.train() # Set text_encoder to train mode regardless of advanced_config
|
||||
|
||||
# Prepare optimizer
|
||||
params_to_optimize = list(unet.parameters()) + list(text_encoder.parameters())
|
||||
optimizer = torch.optim.AdamW(
|
||||
params_to_optimize,
|
||||
lr=advanced_config["learning_rate"],
|
||||
betas=(advanced_config["adam_beta1"], advanced_config["adam_beta2"]),
|
||||
weight_decay=advanced_config["adam_weight_decay"],
|
||||
eps=advanced_config["adam_epsilon"],
|
||||
)
|
||||
|
||||
# Prepare learning rate scheduler
|
||||
lr_scheduler = get_scheduler(
|
||||
advanced_config["lr_scheduler"],
|
||||
optimizer=optimizer,
|
||||
num_warmup_steps=advanced_config["lr_warmup_steps"] * advanced_config["gradient_accumulation_steps"],
|
||||
num_training_steps=advanced_config["max_train_steps"] * advanced_config["gradient_accumulation_steps"],
|
||||
)
|
||||
|
||||
# Prepare for distributed training
|
||||
unet, text_encoder, optimizer, lr_scheduler = accelerator.prepare(unet, text_encoder, optimizer, lr_scheduler)
|
||||
|
||||
# Training loop
|
||||
global_step = 0
|
||||
progress_bar = tqdm(total=advanced_config["max_train_steps"], disable=not accelerator.is_local_main_process)
|
||||
progress_bar.set_description("Training Steps")
|
||||
|
||||
# Wrap the text encoder in our custom module
|
||||
text_encoder = GradientEnabledModule(workspace["pipeline"].text_encoder)
|
||||
|
||||
# Prepare for distributed training
|
||||
unet, text_encoder, optimizer, lr_scheduler = accelerator.prepare(unet, text_encoder, optimizer, lr_scheduler)
|
||||
|
||||
for epoch in range(advanced_config["num_train_epochs"]):
|
||||
for step, batch in enumerate(dataset):
|
||||
with torch.inference_mode(False):
|
||||
with accelerator.accumulate(unet):
|
||||
# Encode text
|
||||
target_input_ids = tokenizer(batch["target_prompt"], return_tensors="pt").input_ids.to(
|
||||
workspace["device"])
|
||||
trigger_input_ids = tokenizer(batch["trigger_prompt"], return_tensors="pt").input_ids.to(
|
||||
workspace["device"])
|
||||
|
||||
# Ensure input_ids are long tensors
|
||||
target_input_ids = target_input_ids.long()
|
||||
trigger_input_ids = trigger_input_ids.long()
|
||||
|
||||
print(f"Target input_ids dtype: {target_input_ids.dtype}")
|
||||
print(f"Trigger input_ids dtype: {trigger_input_ids.dtype}")
|
||||
|
||||
# Forward pass through text encoder
|
||||
with torch.enable_grad():
|
||||
target_encoder_hidden_states = text_encoder(target_input_ids)[0]
|
||||
trigger_encoder_hidden_states = text_encoder(trigger_input_ids)[0]
|
||||
|
||||
print(f"Target hidden states dtype: {target_encoder_hidden_states.dtype}")
|
||||
print(f"Trigger hidden states dtype: {trigger_encoder_hidden_states.dtype}")
|
||||
|
||||
# Ensure hidden states have gradients enabled and are float tensors
|
||||
target_encoder_hidden_states = target_encoder_hidden_states.float().requires_grad_()
|
||||
trigger_encoder_hidden_states = trigger_encoder_hidden_states.float().requires_grad_()
|
||||
|
||||
# Generate initial noise
|
||||
latents = torch.randn(
|
||||
(1, unet.config.in_channels, workspace["resolution"] // 8, workspace["resolution"] // 8),
|
||||
device=workspace["device"],
|
||||
dtype=torch.float32
|
||||
).requires_grad_()
|
||||
|
||||
# Set up timesteps
|
||||
scheduler.set_timesteps(1000)
|
||||
timesteps = scheduler.timesteps
|
||||
|
||||
# Noise schedule loop
|
||||
for i, t in enumerate(timesteps):
|
||||
# Prepare latent input
|
||||
latent_model_input = torch.cat([latents] * 2)
|
||||
latent_model_input = scheduler.scale_model_input(latent_model_input, t)
|
||||
|
||||
# Prepare timestep
|
||||
timestep = torch.tensor([t], dtype=torch.long, device=workspace["device"])
|
||||
|
||||
# Prepare encoder hidden states
|
||||
encoder_hidden_states = torch.cat(
|
||||
[trigger_encoder_hidden_states, target_encoder_hidden_states])
|
||||
|
||||
# Get noise prediction
|
||||
noise_pred = unet(
|
||||
latent_model_input,
|
||||
timestep,
|
||||
encoder_hidden_states=encoder_hidden_states
|
||||
).sample
|
||||
|
||||
# Perform guidance
|
||||
noise_pred_uncond, noise_pred_text = noise_pred.chunk(2)
|
||||
noise_pred = noise_pred_uncond + batch["guidance_scale"] * (
|
||||
noise_pred_text - noise_pred_uncond)
|
||||
|
||||
# Update latents
|
||||
latents = scheduler.step(noise_pred, t, latents).prev_sample
|
||||
|
||||
# Decode latents to image space
|
||||
images = vae.decode(latents / 0.18215).sample
|
||||
|
||||
# Compute loss
|
||||
target_latents = vae.encode(images).latent_dist.sample() * 0.18215
|
||||
loss = F.mse_loss(latents.float(), target_latents.float(), reduction="mean")
|
||||
|
||||
# Backpropagate
|
||||
accelerator.backward(loss)
|
||||
if accelerator.sync_gradients:
|
||||
accelerator.clip_grad_norm_(params_to_optimize, advanced_config["max_grad_norm"])
|
||||
optimizer.step()
|
||||
lr_scheduler.step()
|
||||
optimizer.zero_grad()
|
||||
|
||||
# Check for saving and sampling
|
||||
if accelerator.sync_gradients:
|
||||
global_step += 1
|
||||
if global_step % save_every_n_steps == 0:
|
||||
self.save_checkpoint(accelerator, unet, text_encoder, workspace, global_step,
|
||||
num_checkpoint_limit)
|
||||
|
||||
if global_step % generate_every_n_steps == 0:
|
||||
self.generate_sample(workspace, batch["target_prompt"], batch["trigger_prompt"], global_step)
|
||||
|
||||
progress_bar.update(1)
|
||||
progress_bar.set_postfix(loss=loss.detach().item())
|
||||
|
||||
if global_step >= advanced_config["max_train_steps"]:
|
||||
break
|
||||
|
||||
if global_step >= advanced_config["max_train_steps"]:
|
||||
break
|
||||
|
||||
# Final saves and generations
|
||||
self.save_checkpoint(accelerator, unet, text_encoder, workspace, global_step, num_checkpoint_limit,
|
||||
is_final=True)
|
||||
self.generate_sample(workspace, dataset[0]["target_prompt"], dataset[0]["trigger_prompt"], global_step,
|
||||
is_final=True)
|
||||
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
return ()
|
||||
|
||||
@staticmethod
|
||||
def save_checkpoint(accelerator, unet, text_encoder, workspace, global_step, num_checkpoint_limit, is_final=False):
|
||||
accelerator.wait_for_everyone()
|
||||
if accelerator.is_main_process:
|
||||
unet = accelerator.unwrap_model(unet)
|
||||
lora_state_dict = get_peft_model_state_dict(unet)
|
||||
|
||||
if text_encoder is not None:
|
||||
text_encoder = accelerator.unwrap_model(text_encoder)
|
||||
text_encoder_state_dict = get_peft_model_state_dict(text_encoder)
|
||||
lora_state_dict.update(text_encoder_state_dict)
|
||||
|
||||
os.makedirs(workspace["workspace_dir"], exist_ok=True)
|
||||
checkpoint_dir = os.path.join(workspace["workspace_dir"], "checkpoints")
|
||||
os.makedirs(checkpoint_dir, exist_ok=True)
|
||||
|
||||
if is_final:
|
||||
save_path = os.path.join(workspace["workspace_dir"], "slider_lora_final.safetensors")
|
||||
else:
|
||||
save_path = os.path.join(checkpoint_dir, f"slider_lora_step_{global_step:06d}.safetensors")
|
||||
|
||||
safetensors.torch.save_file(lora_state_dict, save_path)
|
||||
|
||||
# Manage number of checkpoints
|
||||
checkpoints = sorted([f for f in os.listdir(checkpoint_dir) if f.endswith('.safetensors')])
|
||||
while len(checkpoints) > num_checkpoint_limit:
|
||||
os.remove(os.path.join(checkpoint_dir, checkpoints.pop(0)))
|
||||
|
||||
accelerator.wait_for_everyone()
|
||||
|
||||
@staticmethod
|
||||
def generate_sample(workspace, target_prompt, trigger_prompt, global_step, is_final=False):
|
||||
pipeline = workspace["pipeline"]
|
||||
pipeline.to(workspace["device"])
|
||||
|
||||
with torch.no_grad():
|
||||
image = pipeline(
|
||||
prompt=target_prompt,
|
||||
negative_prompt=trigger_prompt,
|
||||
num_inference_steps=30,
|
||||
guidance_scale=7.5,
|
||||
).images[0]
|
||||
|
||||
# Save the image
|
||||
os.makedirs(os.path.join(workspace["workspace_dir"], "samples"), exist_ok=True)
|
||||
if is_final:
|
||||
image_path = os.path.join(workspace["workspace_dir"], "samples", f"final_sample.png")
|
||||
else:
|
||||
image_path = os.path.join(workspace["workspace_dir"], "samples", f"sample_step_{global_step:06d}.png")
|
||||
image.save(image_path)
|
||||
|
||||
pipeline.to("cpu")
|
||||
torch.cuda.empty_cache()
|
||||
+52
@@ -0,0 +1,52 @@
|
||||
# __init__.py
|
||||
|
||||
from .FL_KohyaSSInitWorkspace import FL_KohyaSSInitWorkspace
|
||||
from .FL_KohyaSSDatasetConfig import FL_KohyaSSDatasetConfig
|
||||
from .FL_KohyaSSAdvConfig import FL_KohyaSSAdvConfig
|
||||
from .FL_KohyaSSTrain import FL_KohyaSSTrain
|
||||
from .FL_LoadImagesFromDirectoryPath import FL_LoadImagesFromDirectoryPath
|
||||
#==============================================================================
|
||||
#==============================================================================
|
||||
# from .FL_SliderLoraInitWorkspace import FL_SliderLoraInitWorkspace
|
||||
# from .FL_SliderLoraDatasetConfig import FL_SliderLoraDatasetConfig
|
||||
# from .FL_SliderLoraAdvConfig import FL_SliderLoraAdvConfig
|
||||
# from .FL_SliderLoraTrain import FL_SliderLoraTrain
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"FL_KohyaSSInitWorkspace": FL_KohyaSSInitWorkspace,
|
||||
"FL_KohyaSSDatasetConfig": FL_KohyaSSDatasetConfig,
|
||||
"FL_KohyaSSAdvConfig": FL_KohyaSSAdvConfig,
|
||||
"FL_KohyaSSTrain": FL_KohyaSSTrain,
|
||||
"FL_LoadImagesFromDirectoryPath": FL_LoadImagesFromDirectoryPath,
|
||||
#==============================================================================
|
||||
#==============================================================================
|
||||
# "FL_SliderLoraInitWorkspace": FL_SliderLoraInitWorkspace,
|
||||
# "FL_SliderLoraDatasetConfig": FL_SliderLoraDatasetConfig,
|
||||
# "FL_SliderLoraAdvConfig": FL_SliderLoraAdvConfig,
|
||||
# "FL_SliderLoraTrain": FL_SliderLoraTrain
|
||||
}
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"FL_KohyaSSInitWorkspace": "FL Kohya Workspace",
|
||||
"FL_KohyaSSDatasetConfig": "FL Kohya Dataset Config",
|
||||
"FL_KohyaSSAdvConfig": "FL Kohya Adv Config",
|
||||
"FL_KohyaSSTrain": "FL Kohya Train",
|
||||
"FL_LoadImagesFromDirectoryPath": "FL Kohya Data Loader",
|
||||
#==============================================================================
|
||||
#==============================================================================
|
||||
# "FL_SliderLoraInitWorkspace": "FL Slider LoRA Init Workspace",
|
||||
# "FL_SliderLoraDatasetConfig": "FL Slider LoRA Dataset Config",
|
||||
# "FL_SliderLoraAdvConfig": "FL Slider LoRA Advanced Config",
|
||||
# "FL_SliderLoraTrain": "FL Slider LoRA Train"
|
||||
}
|
||||
ascii_art = """
|
||||
|
||||
MACHINE DELUSIONS
|
||||
TRAINER LOADED
|
||||
|
||||
"""
|
||||
print(ascii_art)
|
||||
|
||||
WEB_DIRECTORY = "./web"
|
||||
__all__ = ["NODE_CLASS_MAPPINGS", "NODE_DISPLAY_NAME_MAPPINGS", "WEB_DIRECTORY"]
|
||||
@@ -0,0 +1,34 @@
|
||||
{
|
||||
"metadata": {
|
||||
"train_type": "lora_sd1_5"
|
||||
},
|
||||
"train_config": {
|
||||
"pretrained_model_name_or_path": "",
|
||||
"max_train_steps": "4500",
|
||||
"xformers": true,
|
||||
"sdpa": false,
|
||||
"fp8_base": false,
|
||||
"mixed_precision": "fp16",
|
||||
"cache_latents": true,
|
||||
"cache_latents_to_disk": true,
|
||||
"network_dim": "16",
|
||||
"network_alpha": "8",
|
||||
"network_module": "networks.lora",
|
||||
"network_train_unet_only": true,
|
||||
"learning_rate": "1e-5",
|
||||
"lr_scheduler": "cosine_with_restarts",
|
||||
"optimizer_type": "AdamW",
|
||||
"save_every_n_epochs": "20",
|
||||
"shuffle_caption": false,
|
||||
"lr_warmup_steps": "0",
|
||||
"save_precision": "fp16",
|
||||
"lr_scheduler_num_cycles": "1",
|
||||
"persistent_data_loader_workers": true,
|
||||
"no_metadata": true,
|
||||
"noise_offset": "0.1",
|
||||
"output_dir": "",
|
||||
"output_name": "",
|
||||
"no_half_vae": true,
|
||||
"lowram": false
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,34 @@
|
||||
{
|
||||
"metadata": {
|
||||
"train_type": "lora_sdxl"
|
||||
},
|
||||
"train_config": {
|
||||
"pretrained_model_name_or_path": "",
|
||||
"max_train_steps": "4500",
|
||||
"xformers": true,
|
||||
"sdpa": false,
|
||||
"fp8_base": false,
|
||||
"mixed_precision": "fp16",
|
||||
"cache_latents": true,
|
||||
"cache_latents_to_disk": true,
|
||||
"network_dim": "16",
|
||||
"network_alpha": "8",
|
||||
"network_module": "networks.lora",
|
||||
"network_train_unet_only": true,
|
||||
"learning_rate": "1e-5",
|
||||
"lr_scheduler": "cosine_with_restarts",
|
||||
"optimizer_type": "AdamW",
|
||||
"save_every_n_epochs": "20",
|
||||
"shuffle_caption": false,
|
||||
"lr_warmup_steps": "0",
|
||||
"save_precision": "fp16",
|
||||
"lr_scheduler_num_cycles": "1",
|
||||
"persistent_data_loader_workers": true,
|
||||
"no_metadata": true,
|
||||
"noise_offset": "0.1",
|
||||
"output_dir": "",
|
||||
"output_name": "",
|
||||
"no_half_vae": true,
|
||||
"lowram": false
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,34 @@
|
||||
{
|
||||
"unk_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"single_word": false,
|
||||
"lstrip": false,
|
||||
"rstrip": false,
|
||||
"normalized": true,
|
||||
"__type": "AddedToken"
|
||||
},
|
||||
"bos_token": {
|
||||
"content": "<|startoftext|>",
|
||||
"single_word": false,
|
||||
"lstrip": false,
|
||||
"rstrip": false,
|
||||
"normalized": true,
|
||||
"__type": "AddedToken"
|
||||
},
|
||||
"eos_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"single_word": false,
|
||||
"lstrip": false,
|
||||
"rstrip": false,
|
||||
"normalized": true,
|
||||
"__type": "AddedToken"
|
||||
},
|
||||
"pad_token": "<|endoftext|>",
|
||||
"add_prefix_space": false,
|
||||
"errors": "replace",
|
||||
"do_lower_case": true,
|
||||
"name_or_path": "openai/clip-vit-base-patch32",
|
||||
"model_max_length": 77,
|
||||
"special_tokens_map_file": "./special_tokens_map.json",
|
||||
"tokenizer_class": "CLIPTokenizer"
|
||||
}
|
||||
@@ -0,0 +1,207 @@
|
||||
---
|
||||
license: creativeml-openrail-m
|
||||
tags:
|
||||
- stable-diffusion
|
||||
- stable-diffusion-diffusers
|
||||
- text-to-image
|
||||
inference: true
|
||||
extra_gated_prompt: |-
|
||||
This model is open access and available to all, with a CreativeML OpenRAIL-M license further specifying rights and usage.
|
||||
The CreativeML OpenRAIL License specifies:
|
||||
|
||||
1. You can't use the model to deliberately produce nor share illegal or harmful outputs or content
|
||||
2. CompVis claims no rights on the outputs you generate, you are free to use them and are accountable for their use which must not go against the provisions set in the license
|
||||
3. You may re-distribute the weights and use the model commercially and/or as a service. If you do, please be aware you have to include the same use restrictions as the ones in the license and share a copy of the CreativeML OpenRAIL-M to all your users (please read the license entirely and carefully)
|
||||
Please read the full license carefully here: https://huggingface.co/spaces/CompVis/stable-diffusion-license
|
||||
|
||||
extra_gated_heading: Please read the LICENSE to access this model
|
||||
---
|
||||
|
||||
# Stable Diffusion v1-5 Model Card
|
||||
|
||||
Stable Diffusion is a latent text-to-image diffusion model capable of generating photo-realistic images given any text input.
|
||||
For more information about how Stable Diffusion functions, please have a look at [🤗's Stable Diffusion blog](https://huggingface.co/blog/stable_diffusion).
|
||||
|
||||
The **Stable-Diffusion-v1-5** checkpoint was initialized with the weights of the [Stable-Diffusion-v1-2](https:/steps/huggingface.co/CompVis/stable-diffusion-v1-2)
|
||||
checkpoint and subsequently fine-tuned on 595k steps at resolution 512x512 on "laion-aesthetics v2 5+" and 10% dropping of the text-conditioning to improve [classifier-free guidance sampling](https://arxiv.org/abs/2207.12598).
|
||||
|
||||
You can use this both with the [🧨Diffusers library](https://github.com/huggingface/diffusers) and the [RunwayML GitHub repository](https://github.com/runwayml/stable-diffusion).
|
||||
|
||||
### Diffusers
|
||||
```py
|
||||
from diffusers import StableDiffusionPipeline
|
||||
import torch
|
||||
|
||||
model_id = "runwayml/stable-diffusion-v1-5"
|
||||
pipe = StableDiffusionPipeline.from_pretrained(model_id, torch_dtype=torch.float16)
|
||||
pipe = pipe.to("cuda")
|
||||
|
||||
prompt = "a photo of an astronaut riding a horse on mars"
|
||||
image = pipe(prompt).images[0]
|
||||
|
||||
image.save("astronaut_rides_horse.png")
|
||||
```
|
||||
For more detailed instructions, use-cases and examples in JAX follow the instructions [here](https://github.com/huggingface/diffusers#text-to-image-generation-with-stable-diffusion)
|
||||
|
||||
### Original GitHub Repository
|
||||
|
||||
1. Download the weights
|
||||
- [v1-5-pruned-emaonly.ckpt](https://huggingface.co/runwayml/stable-diffusion-v1-5/resolve/main/v1-5-pruned-emaonly.ckpt) - 4.27GB, ema-only weight. uses less VRAM - suitable for inference
|
||||
- [v1-5-pruned.ckpt](https://huggingface.co/runwayml/stable-diffusion-v1-5/resolve/main/v1-5-pruned.ckpt) - 7.7GB, ema+non-ema weights. uses more VRAM - suitable for fine-tuning
|
||||
|
||||
2. Follow instructions [here](https://github.com/runwayml/stable-diffusion).
|
||||
|
||||
## Model Details
|
||||
- **Developed by:** Robin Rombach, Patrick Esser
|
||||
- **Model type:** Diffusion-based text-to-image generation model
|
||||
- **Language(s):** English
|
||||
- **License:** [The CreativeML OpenRAIL M license](https://huggingface.co/spaces/CompVis/stable-diffusion-license) is an [Open RAIL M license](https://www.licenses.ai/blog/2022/8/18/naming-convention-of-responsible-ai-licenses), adapted from the work that [BigScience](https://bigscience.huggingface.co/) and [the RAIL Initiative](https://www.licenses.ai/) are jointly carrying in the area of responsible AI licensing. See also [the article about the BLOOM Open RAIL license](https://bigscience.huggingface.co/blog/the-bigscience-rail-license) on which our license is based.
|
||||
- **Model Description:** This is a model that can be used to generate and modify images based on text prompts. It is a [Latent Diffusion Model](https://arxiv.org/abs/2112.10752) that uses a fixed, pretrained text encoder ([CLIP ViT-L/14](https://arxiv.org/abs/2103.00020)) as suggested in the [Imagen paper](https://arxiv.org/abs/2205.11487).
|
||||
- **Resources for more information:** [GitHub Repository](https://github.com/CompVis/stable-diffusion), [Paper](https://arxiv.org/abs/2112.10752).
|
||||
- **Cite as:**
|
||||
|
||||
@InProceedings{Rombach_2022_CVPR,
|
||||
author = {Rombach, Robin and Blattmann, Andreas and Lorenz, Dominik and Esser, Patrick and Ommer, Bj\"orn},
|
||||
title = {High-Resolution Image Synthesis With Latent Diffusion Models},
|
||||
booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
|
||||
month = {June},
|
||||
year = {2022},
|
||||
pages = {10684-10695}
|
||||
}
|
||||
|
||||
# Uses
|
||||
|
||||
## Direct Use
|
||||
The model is intended for research purposes only. Possible research areas and
|
||||
tasks include
|
||||
|
||||
- Safe deployment of models which have the potential to generate harmful content.
|
||||
- Probing and understanding the limitations and biases of generative models.
|
||||
- Generation of artworks and use in design and other artistic processes.
|
||||
- Applications in educational or creative tools.
|
||||
- Research on generative models.
|
||||
|
||||
Excluded uses are described below.
|
||||
|
||||
### Misuse, Malicious Use, and Out-of-Scope Use
|
||||
_Note: This section is taken from the [DALLE-MINI model card](https://huggingface.co/dalle-mini/dalle-mini), but applies in the same way to Stable Diffusion v1_.
|
||||
|
||||
|
||||
The model should not be used to intentionally create or disseminate images that create hostile or alienating environments for people. This includes generating images that people would foreseeably find disturbing, distressing, or offensive; or content that propagates historical or current stereotypes.
|
||||
|
||||
#### Out-of-Scope Use
|
||||
The model was not trained to be factual or true representations of people or events, and therefore using the model to generate such content is out-of-scope for the abilities of this model.
|
||||
|
||||
#### Misuse and Malicious Use
|
||||
Using the model to generate content that is cruel to individuals is a misuse of this model. This includes, but is not limited to:
|
||||
|
||||
- Generating demeaning, dehumanizing, or otherwise harmful representations of people or their environments, cultures, religions, etc.
|
||||
- Intentionally promoting or propagating discriminatory content or harmful stereotypes.
|
||||
- Impersonating individuals without their consent.
|
||||
- Sexual content without consent of the people who might see it.
|
||||
- Mis- and disinformation
|
||||
- Representations of egregious violence and gore
|
||||
- Sharing of copyrighted or licensed material in violation of its terms of use.
|
||||
- Sharing content that is an alteration of copyrighted or licensed material in violation of its terms of use.
|
||||
|
||||
## Limitations and Bias
|
||||
|
||||
### Limitations
|
||||
|
||||
- The model does not achieve perfect photorealism
|
||||
- The model cannot render legible text
|
||||
- The model does not perform well on more difficult tasks which involve compositionality, such as rendering an image corresponding to “A red cube on top of a blue sphere”
|
||||
- Faces and people in general may not be generated properly.
|
||||
- The model was trained mainly with English captions and will not work as well in other languages.
|
||||
- The autoencoding part of the model is lossy
|
||||
- The model was trained on a large-scale dataset
|
||||
[LAION-5B](https://laion.ai/blog/laion-5b/) which contains adult material
|
||||
and is not fit for product use without additional safety mechanisms and
|
||||
considerations.
|
||||
- No additional measures were used to deduplicate the dataset. As a result, we observe some degree of memorization for images that are duplicated in the training data.
|
||||
The training data can be searched at [https://rom1504.github.io/clip-retrieval/](https://rom1504.github.io/clip-retrieval/) to possibly assist in the detection of memorized images.
|
||||
|
||||
### Bias
|
||||
|
||||
While the capabilities of image generation models are impressive, they can also reinforce or exacerbate social biases.
|
||||
Stable Diffusion v1 was trained on subsets of [LAION-2B(en)](https://laion.ai/blog/laion-5b/),
|
||||
which consists of images that are primarily limited to English descriptions.
|
||||
Texts and images from communities and cultures that use other languages are likely to be insufficiently accounted for.
|
||||
This affects the overall output of the model, as white and western cultures are often set as the default. Further, the
|
||||
ability of the model to generate content with non-English prompts is significantly worse than with English-language prompts.
|
||||
|
||||
### Safety Module
|
||||
|
||||
The intended use of this model is with the [Safety Checker](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/safety_checker.py) in Diffusers.
|
||||
This checker works by checking model outputs against known hard-coded NSFW concepts.
|
||||
The concepts are intentionally hidden to reduce the likelihood of reverse-engineering this filter.
|
||||
Specifically, the checker compares the class probability of harmful concepts in the embedding space of the `CLIPTextModel` *after generation* of the images.
|
||||
The concepts are passed into the model with the generated image and compared to a hand-engineered weight for each NSFW concept.
|
||||
|
||||
|
||||
## Training
|
||||
|
||||
**Training Data**
|
||||
The model developers used the following dataset for training the model:
|
||||
|
||||
- LAION-2B (en) and subsets thereof (see next section)
|
||||
|
||||
**Training Procedure**
|
||||
Stable Diffusion v1-5 is a latent diffusion model which combines an autoencoder with a diffusion model that is trained in the latent space of the autoencoder. During training,
|
||||
|
||||
- Images are encoded through an encoder, which turns images into latent representations. The autoencoder uses a relative downsampling factor of 8 and maps images of shape H x W x 3 to latents of shape H/f x W/f x 4
|
||||
- Text prompts are encoded through a ViT-L/14 text-encoder.
|
||||
- The non-pooled output of the text encoder is fed into the UNet backbone of the latent diffusion model via cross-attention.
|
||||
- The loss is a reconstruction objective between the noise that was added to the latent and the prediction made by the UNet.
|
||||
|
||||
Currently six Stable Diffusion checkpoints are provided, which were trained as follows.
|
||||
- [`stable-diffusion-v1-1`](https://huggingface.co/CompVis/stable-diffusion-v1-1): 237,000 steps at resolution `256x256` on [laion2B-en](https://huggingface.co/datasets/laion/laion2B-en).
|
||||
194,000 steps at resolution `512x512` on [laion-high-resolution](https://huggingface.co/datasets/laion/laion-high-resolution) (170M examples from LAION-5B with resolution `>= 1024x1024`).
|
||||
- [`stable-diffusion-v1-2`](https://huggingface.co/CompVis/stable-diffusion-v1-2): Resumed from `stable-diffusion-v1-1`.
|
||||
515,000 steps at resolution `512x512` on "laion-improved-aesthetics" (a subset of laion2B-en,
|
||||
filtered to images with an original size `>= 512x512`, estimated aesthetics score `> 5.0`, and an estimated watermark probability `< 0.5`. The watermark estimate is from the LAION-5B metadata, the aesthetics score is estimated using an [improved aesthetics estimator](https://github.com/christophschuhmann/improved-aesthetic-predictor)).
|
||||
- [`stable-diffusion-v1-3`](https://huggingface.co/CompVis/stable-diffusion-v1-3): Resumed from `stable-diffusion-v1-2` - 195,000 steps at resolution `512x512` on "laion-improved-aesthetics" and 10 % dropping of the text-conditioning to improve [classifier-free guidance sampling](https://arxiv.org/abs/2207.12598).
|
||||
- [`stable-diffusion-v1-4`](https://huggingface.co/CompVis/stable-diffusion-v1-4) Resumed from `stable-diffusion-v1-2` - 225,000 steps at resolution `512x512` on "laion-aesthetics v2 5+" and 10 % dropping of the text-conditioning to improve [classifier-free guidance sampling](https://arxiv.org/abs/2207.12598).
|
||||
- [`stable-diffusion-v1-5`](https://huggingface.co/runwayml/stable-diffusion-v1-5) Resumed from `stable-diffusion-v1-2` - 595,000 steps at resolution `512x512` on "laion-aesthetics v2 5+" and 10 % dropping of the text-conditioning to improve [classifier-free guidance sampling](https://arxiv.org/abs/2207.12598).
|
||||
- [`stable-diffusion-inpainting`](https://huggingface.co/runwayml/stable-diffusion-inpainting) Resumed from `stable-diffusion-v1-5` - then 440,000 steps of inpainting training at resolution 512x512 on “laion-aesthetics v2 5+” and 10% dropping of the text-conditioning. For inpainting, the UNet has 5 additional input channels (4 for the encoded masked-image and 1 for the mask itself) whose weights were zero-initialized after restoring the non-inpainting checkpoint. During training, we generate synthetic masks and in 25% mask everything.
|
||||
|
||||
- **Hardware:** 32 x 8 x A100 GPUs
|
||||
- **Optimizer:** AdamW
|
||||
- **Gradient Accumulations**: 2
|
||||
- **Batch:** 32 x 8 x 2 x 4 = 2048
|
||||
- **Learning rate:** warmup to 0.0001 for 10,000 steps and then kept constant
|
||||
|
||||
## Evaluation Results
|
||||
Evaluations with different classifier-free guidance scales (1.5, 2.0, 3.0, 4.0,
|
||||
5.0, 6.0, 7.0, 8.0) and 50 PNDM/PLMS sampling
|
||||
steps show the relative improvements of the checkpoints:
|
||||
|
||||
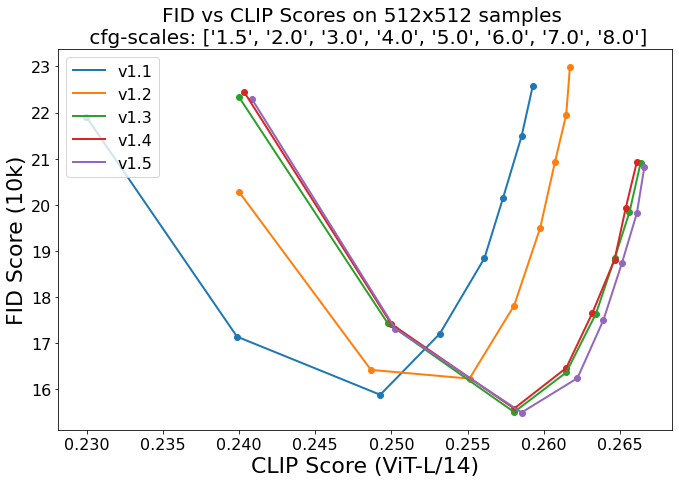
|
||||
|
||||
Evaluated using 50 PLMS steps and 10000 random prompts from the COCO2017 validation set, evaluated at 512x512 resolution. Not optimized for FID scores.
|
||||
## Environmental Impact
|
||||
|
||||
**Stable Diffusion v1** **Estimated Emissions**
|
||||
Based on that information, we estimate the following CO2 emissions using the [Machine Learning Impact calculator](https://mlco2.github.io/impact#compute) presented in [Lacoste et al. (2019)](https://arxiv.org/abs/1910.09700). The hardware, runtime, cloud provider, and compute region were utilized to estimate the carbon impact.
|
||||
|
||||
- **Hardware Type:** A100 PCIe 40GB
|
||||
- **Hours used:** 150000
|
||||
- **Cloud Provider:** AWS
|
||||
- **Compute Region:** US-east
|
||||
- **Carbon Emitted (Power consumption x Time x Carbon produced based on location of power grid):** 11250 kg CO2 eq.
|
||||
|
||||
|
||||
## Citation
|
||||
|
||||
```bibtex
|
||||
@InProceedings{Rombach_2022_CVPR,
|
||||
author = {Rombach, Robin and Blattmann, Andreas and Lorenz, Dominik and Esser, Patrick and Ommer, Bj\"orn},
|
||||
title = {High-Resolution Image Synthesis With Latent Diffusion Models},
|
||||
booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
|
||||
month = {June},
|
||||
year = {2022},
|
||||
pages = {10684-10695}
|
||||
}
|
||||
```
|
||||
|
||||
*This model card was written by: Robin Rombach and Patrick Esser and is based on the [DALL-E Mini model card](https://huggingface.co/dalle-mini/dalle-mini).*
|
||||
+20
@@ -0,0 +1,20 @@
|
||||
{
|
||||
"crop_size": 224,
|
||||
"do_center_crop": true,
|
||||
"do_convert_rgb": true,
|
||||
"do_normalize": true,
|
||||
"do_resize": true,
|
||||
"feature_extractor_type": "CLIPFeatureExtractor",
|
||||
"image_mean": [
|
||||
0.48145466,
|
||||
0.4578275,
|
||||
0.40821073
|
||||
],
|
||||
"image_std": [
|
||||
0.26862954,
|
||||
0.26130258,
|
||||
0.27577711
|
||||
],
|
||||
"resample": 3,
|
||||
"size": 224
|
||||
}
|
||||
@@ -0,0 +1,32 @@
|
||||
{
|
||||
"_class_name": "StableDiffusionPipeline",
|
||||
"_diffusers_version": "0.6.0",
|
||||
"feature_extractor": [
|
||||
"transformers",
|
||||
"CLIPImageProcessor"
|
||||
],
|
||||
"safety_checker": [
|
||||
"stable_diffusion",
|
||||
"StableDiffusionSafetyChecker"
|
||||
],
|
||||
"scheduler": [
|
||||
"diffusers",
|
||||
"PNDMScheduler"
|
||||
],
|
||||
"text_encoder": [
|
||||
"transformers",
|
||||
"CLIPTextModel"
|
||||
],
|
||||
"tokenizer": [
|
||||
"transformers",
|
||||
"CLIPTokenizer"
|
||||
],
|
||||
"unet": [
|
||||
"diffusers",
|
||||
"UNet2DConditionModel"
|
||||
],
|
||||
"vae": [
|
||||
"diffusers",
|
||||
"AutoencoderKL"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,175 @@
|
||||
{
|
||||
"_commit_hash": "4bb648a606ef040e7685bde262611766a5fdd67b",
|
||||
"_name_or_path": "CompVis/stable-diffusion-safety-checker",
|
||||
"architectures": [
|
||||
"StableDiffusionSafetyChecker"
|
||||
],
|
||||
"initializer_factor": 1.0,
|
||||
"logit_scale_init_value": 2.6592,
|
||||
"model_type": "clip",
|
||||
"projection_dim": 768,
|
||||
"text_config": {
|
||||
"_name_or_path": "",
|
||||
"add_cross_attention": false,
|
||||
"architectures": null,
|
||||
"attention_dropout": 0.0,
|
||||
"bad_words_ids": null,
|
||||
"bos_token_id": 0,
|
||||
"chunk_size_feed_forward": 0,
|
||||
"cross_attention_hidden_size": null,
|
||||
"decoder_start_token_id": null,
|
||||
"diversity_penalty": 0.0,
|
||||
"do_sample": false,
|
||||
"dropout": 0.0,
|
||||
"early_stopping": false,
|
||||
"encoder_no_repeat_ngram_size": 0,
|
||||
"eos_token_id": 2,
|
||||
"exponential_decay_length_penalty": null,
|
||||
"finetuning_task": null,
|
||||
"forced_bos_token_id": null,
|
||||
"forced_eos_token_id": null,
|
||||
"hidden_act": "quick_gelu",
|
||||
"hidden_size": 768,
|
||||
"id2label": {
|
||||
"0": "LABEL_0",
|
||||
"1": "LABEL_1"
|
||||
},
|
||||
"initializer_factor": 1.0,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 3072,
|
||||
"is_decoder": false,
|
||||
"is_encoder_decoder": false,
|
||||
"label2id": {
|
||||
"LABEL_0": 0,
|
||||
"LABEL_1": 1
|
||||
},
|
||||
"layer_norm_eps": 1e-05,
|
||||
"length_penalty": 1.0,
|
||||
"max_length": 20,
|
||||
"max_position_embeddings": 77,
|
||||
"min_length": 0,
|
||||
"model_type": "clip_text_model",
|
||||
"no_repeat_ngram_size": 0,
|
||||
"num_attention_heads": 12,
|
||||
"num_beam_groups": 1,
|
||||
"num_beams": 1,
|
||||
"num_hidden_layers": 12,
|
||||
"num_return_sequences": 1,
|
||||
"output_attentions": false,
|
||||
"output_hidden_states": false,
|
||||
"output_scores": false,
|
||||
"pad_token_id": 1,
|
||||
"prefix": null,
|
||||
"problem_type": null,
|
||||
"pruned_heads": {},
|
||||
"remove_invalid_values": false,
|
||||
"repetition_penalty": 1.0,
|
||||
"return_dict": true,
|
||||
"return_dict_in_generate": false,
|
||||
"sep_token_id": null,
|
||||
"task_specific_params": null,
|
||||
"temperature": 1.0,
|
||||
"tf_legacy_loss": false,
|
||||
"tie_encoder_decoder": false,
|
||||
"tie_word_embeddings": true,
|
||||
"tokenizer_class": null,
|
||||
"top_k": 50,
|
||||
"top_p": 1.0,
|
||||
"torch_dtype": null,
|
||||
"torchscript": false,
|
||||
"transformers_version": "4.22.0.dev0",
|
||||
"typical_p": 1.0,
|
||||
"use_bfloat16": false,
|
||||
"vocab_size": 49408
|
||||
},
|
||||
"text_config_dict": {
|
||||
"hidden_size": 768,
|
||||
"intermediate_size": 3072,
|
||||
"num_attention_heads": 12,
|
||||
"num_hidden_layers": 12
|
||||
},
|
||||
"torch_dtype": "float32",
|
||||
"transformers_version": null,
|
||||
"vision_config": {
|
||||
"_name_or_path": "",
|
||||
"add_cross_attention": false,
|
||||
"architectures": null,
|
||||
"attention_dropout": 0.0,
|
||||
"bad_words_ids": null,
|
||||
"bos_token_id": null,
|
||||
"chunk_size_feed_forward": 0,
|
||||
"cross_attention_hidden_size": null,
|
||||
"decoder_start_token_id": null,
|
||||
"diversity_penalty": 0.0,
|
||||
"do_sample": false,
|
||||
"dropout": 0.0,
|
||||
"early_stopping": false,
|
||||
"encoder_no_repeat_ngram_size": 0,
|
||||
"eos_token_id": null,
|
||||
"exponential_decay_length_penalty": null,
|
||||
"finetuning_task": null,
|
||||
"forced_bos_token_id": null,
|
||||
"forced_eos_token_id": null,
|
||||
"hidden_act": "quick_gelu",
|
||||
"hidden_size": 1024,
|
||||
"id2label": {
|
||||
"0": "LABEL_0",
|
||||
"1": "LABEL_1"
|
||||
},
|
||||
"image_size": 224,
|
||||
"initializer_factor": 1.0,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 4096,
|
||||
"is_decoder": false,
|
||||
"is_encoder_decoder": false,
|
||||
"label2id": {
|
||||
"LABEL_0": 0,
|
||||
"LABEL_1": 1
|
||||
},
|
||||
"layer_norm_eps": 1e-05,
|
||||
"length_penalty": 1.0,
|
||||
"max_length": 20,
|
||||
"min_length": 0,
|
||||
"model_type": "clip_vision_model",
|
||||
"no_repeat_ngram_size": 0,
|
||||
"num_attention_heads": 16,
|
||||
"num_beam_groups": 1,
|
||||
"num_beams": 1,
|
||||
"num_channels": 3,
|
||||
"num_hidden_layers": 24,
|
||||
"num_return_sequences": 1,
|
||||
"output_attentions": false,
|
||||
"output_hidden_states": false,
|
||||
"output_scores": false,
|
||||
"pad_token_id": null,
|
||||
"patch_size": 14,
|
||||
"prefix": null,
|
||||
"problem_type": null,
|
||||
"pruned_heads": {},
|
||||
"remove_invalid_values": false,
|
||||
"repetition_penalty": 1.0,
|
||||
"return_dict": true,
|
||||
"return_dict_in_generate": false,
|
||||
"sep_token_id": null,
|
||||
"task_specific_params": null,
|
||||
"temperature": 1.0,
|
||||
"tf_legacy_loss": false,
|
||||
"tie_encoder_decoder": false,
|
||||
"tie_word_embeddings": true,
|
||||
"tokenizer_class": null,
|
||||
"top_k": 50,
|
||||
"top_p": 1.0,
|
||||
"torch_dtype": null,
|
||||
"torchscript": false,
|
||||
"transformers_version": "4.22.0.dev0",
|
||||
"typical_p": 1.0,
|
||||
"use_bfloat16": false
|
||||
},
|
||||
"vision_config_dict": {
|
||||
"hidden_size": 1024,
|
||||
"intermediate_size": 4096,
|
||||
"num_attention_heads": 16,
|
||||
"num_hidden_layers": 24,
|
||||
"patch_size": 14
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,13 @@
|
||||
{
|
||||
"_class_name": "PNDMScheduler",
|
||||
"_diffusers_version": "0.6.0",
|
||||
"beta_end": 0.012,
|
||||
"beta_schedule": "scaled_linear",
|
||||
"beta_start": 0.00085,
|
||||
"num_train_timesteps": 1000,
|
||||
"set_alpha_to_one": false,
|
||||
"skip_prk_steps": true,
|
||||
"steps_offset": 1,
|
||||
"trained_betas": null,
|
||||
"clip_sample": false
|
||||
}
|
||||
@@ -0,0 +1,25 @@
|
||||
{
|
||||
"_name_or_path": "openai/clip-vit-large-patch14",
|
||||
"architectures": [
|
||||
"CLIPTextModel"
|
||||
],
|
||||
"attention_dropout": 0.0,
|
||||
"bos_token_id": 0,
|
||||
"dropout": 0.0,
|
||||
"eos_token_id": 2,
|
||||
"hidden_act": "quick_gelu",
|
||||
"hidden_size": 768,
|
||||
"initializer_factor": 1.0,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 3072,
|
||||
"layer_norm_eps": 1e-05,
|
||||
"max_position_embeddings": 77,
|
||||
"model_type": "clip_text_model",
|
||||
"num_attention_heads": 12,
|
||||
"num_hidden_layers": 12,
|
||||
"pad_token_id": 1,
|
||||
"projection_dim": 768,
|
||||
"torch_dtype": "float32",
|
||||
"transformers_version": "4.22.0.dev0",
|
||||
"vocab_size": 49408
|
||||
}
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,24 @@
|
||||
{
|
||||
"bos_token": {
|
||||
"content": "<|startoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"eos_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"pad_token": "<|endoftext|>",
|
||||
"unk_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,34 @@
|
||||
{
|
||||
"add_prefix_space": false,
|
||||
"bos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|startoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"do_lower_case": true,
|
||||
"eos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"errors": "replace",
|
||||
"model_max_length": 77,
|
||||
"name_or_path": "openai/clip-vit-large-patch14",
|
||||
"pad_token": "<|endoftext|>",
|
||||
"special_tokens_map_file": "./special_tokens_map.json",
|
||||
"tokenizer_class": "CLIPTokenizer",
|
||||
"unk_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,36 @@
|
||||
{
|
||||
"_class_name": "UNet2DConditionModel",
|
||||
"_diffusers_version": "0.6.0",
|
||||
"act_fn": "silu",
|
||||
"attention_head_dim": 8,
|
||||
"block_out_channels": [
|
||||
320,
|
||||
640,
|
||||
1280,
|
||||
1280
|
||||
],
|
||||
"center_input_sample": false,
|
||||
"cross_attention_dim": 768,
|
||||
"down_block_types": [
|
||||
"CrossAttnDownBlock2D",
|
||||
"CrossAttnDownBlock2D",
|
||||
"CrossAttnDownBlock2D",
|
||||
"DownBlock2D"
|
||||
],
|
||||
"downsample_padding": 1,
|
||||
"flip_sin_to_cos": true,
|
||||
"freq_shift": 0,
|
||||
"in_channels": 4,
|
||||
"layers_per_block": 2,
|
||||
"mid_block_scale_factor": 1,
|
||||
"norm_eps": 1e-05,
|
||||
"norm_num_groups": 32,
|
||||
"out_channels": 4,
|
||||
"sample_size": 64,
|
||||
"up_block_types": [
|
||||
"UpBlock2D",
|
||||
"CrossAttnUpBlock2D",
|
||||
"CrossAttnUpBlock2D",
|
||||
"CrossAttnUpBlock2D"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,70 @@
|
||||
model:
|
||||
base_learning_rate: 1.0e-04
|
||||
target: ldm.models.diffusion.ddpm.LatentDiffusion
|
||||
params:
|
||||
linear_start: 0.00085
|
||||
linear_end: 0.0120
|
||||
num_timesteps_cond: 1
|
||||
log_every_t: 200
|
||||
timesteps: 1000
|
||||
first_stage_key: "jpg"
|
||||
cond_stage_key: "txt"
|
||||
image_size: 64
|
||||
channels: 4
|
||||
cond_stage_trainable: false # Note: different from the one we trained before
|
||||
conditioning_key: crossattn
|
||||
monitor: val/loss_simple_ema
|
||||
scale_factor: 0.18215
|
||||
use_ema: False
|
||||
|
||||
scheduler_config: # 10000 warmup steps
|
||||
target: ldm.lr_scheduler.LambdaLinearScheduler
|
||||
params:
|
||||
warm_up_steps: [ 10000 ]
|
||||
cycle_lengths: [ 10000000000000 ] # incredibly large number to prevent corner cases
|
||||
f_start: [ 1.e-6 ]
|
||||
f_max: [ 1. ]
|
||||
f_min: [ 1. ]
|
||||
|
||||
unet_config:
|
||||
target: ldm.modules.diffusionmodules.openaimodel.UNetModel
|
||||
params:
|
||||
image_size: 32 # unused
|
||||
in_channels: 4
|
||||
out_channels: 4
|
||||
model_channels: 320
|
||||
attention_resolutions: [ 4, 2, 1 ]
|
||||
num_res_blocks: 2
|
||||
channel_mult: [ 1, 2, 4, 4 ]
|
||||
num_heads: 8
|
||||
use_spatial_transformer: True
|
||||
transformer_depth: 1
|
||||
context_dim: 768
|
||||
use_checkpoint: True
|
||||
legacy: False
|
||||
|
||||
first_stage_config:
|
||||
target: ldm.models.autoencoder.AutoencoderKL
|
||||
params:
|
||||
embed_dim: 4
|
||||
monitor: val/rec_loss
|
||||
ddconfig:
|
||||
double_z: true
|
||||
z_channels: 4
|
||||
resolution: 256
|
||||
in_channels: 3
|
||||
out_ch: 3
|
||||
ch: 128
|
||||
ch_mult:
|
||||
- 1
|
||||
- 2
|
||||
- 4
|
||||
- 4
|
||||
num_res_blocks: 2
|
||||
attn_resolutions: []
|
||||
dropout: 0.0
|
||||
lossconfig:
|
||||
target: torch.nn.Identity
|
||||
|
||||
cond_stage_config:
|
||||
target: ldm.modules.encoders.modules.FrozenCLIPEmbedder
|
||||
@@ -0,0 +1,29 @@
|
||||
{
|
||||
"_class_name": "AutoencoderKL",
|
||||
"_diffusers_version": "0.6.0",
|
||||
"act_fn": "silu",
|
||||
"block_out_channels": [
|
||||
128,
|
||||
256,
|
||||
512,
|
||||
512
|
||||
],
|
||||
"down_block_types": [
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D"
|
||||
],
|
||||
"in_channels": 3,
|
||||
"latent_channels": 4,
|
||||
"layers_per_block": 2,
|
||||
"norm_num_groups": 32,
|
||||
"out_channels": 3,
|
||||
"sample_size": 512,
|
||||
"up_block_types": [
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,70 @@
|
||||
model:
|
||||
base_learning_rate: 1.0e-04
|
||||
target: ldm.models.diffusion.ddpm.LatentDiffusion
|
||||
params:
|
||||
linear_start: 0.00085
|
||||
linear_end: 0.0120
|
||||
num_timesteps_cond: 1
|
||||
log_every_t: 200
|
||||
timesteps: 1000
|
||||
first_stage_key: "jpg"
|
||||
cond_stage_key: "txt"
|
||||
image_size: 64
|
||||
channels: 4
|
||||
cond_stage_trainable: false # Note: different from the one we trained before
|
||||
conditioning_key: crossattn
|
||||
monitor: val/loss_simple_ema
|
||||
scale_factor: 0.18215
|
||||
use_ema: False
|
||||
|
||||
scheduler_config: # 10000 warmup steps
|
||||
target: ldm.lr_scheduler.LambdaLinearScheduler
|
||||
params:
|
||||
warm_up_steps: [ 10000 ]
|
||||
cycle_lengths: [ 10000000000000 ] # incredibly large number to prevent corner cases
|
||||
f_start: [ 1.e-6 ]
|
||||
f_max: [ 1. ]
|
||||
f_min: [ 1. ]
|
||||
|
||||
unet_config:
|
||||
target: ldm.modules.diffusionmodules.openaimodel.UNetModel
|
||||
params:
|
||||
image_size: 32 # unused
|
||||
in_channels: 4
|
||||
out_channels: 4
|
||||
model_channels: 320
|
||||
attention_resolutions: [ 4, 2, 1 ]
|
||||
num_res_blocks: 2
|
||||
channel_mult: [ 1, 2, 4, 4 ]
|
||||
num_heads: 8
|
||||
use_spatial_transformer: True
|
||||
transformer_depth: 1
|
||||
context_dim: 768
|
||||
use_checkpoint: True
|
||||
legacy: False
|
||||
|
||||
first_stage_config:
|
||||
target: ldm.models.autoencoder.AutoencoderKL
|
||||
params:
|
||||
embed_dim: 4
|
||||
monitor: val/rec_loss
|
||||
ddconfig:
|
||||
double_z: true
|
||||
z_channels: 4
|
||||
resolution: 256
|
||||
in_channels: 3
|
||||
out_ch: 3
|
||||
ch: 128
|
||||
ch_mult:
|
||||
- 1
|
||||
- 2
|
||||
- 4
|
||||
- 4
|
||||
num_res_blocks: 2
|
||||
attn_resolutions: []
|
||||
dropout: 0.0
|
||||
lossconfig:
|
||||
target: torch.nn.Identity
|
||||
|
||||
cond_stage_config:
|
||||
target: ldm.modules.encoders.modules.FrozenCLIPEmbedder
|
||||
@@ -0,0 +1,60 @@
|
||||
Copyright (c) 2023 Stability AI
|
||||
CreativeML Open RAIL++-M License dated July 26, 2023
|
||||
|
||||
Section I: PREAMBLE
|
||||
Multimodal generative models are being widely adopted and used, and have the potential to transform the way artists, among other individuals, conceive and benefit from AI or ML technologies as a tool for content creation.
|
||||
Notwithstanding the current and potential benefits that these artifacts can bring to society at large, there are also concerns about potential misuses of them, either due to their technical limitations or ethical considerations.
|
||||
In short, this license strives for both the open and responsible downstream use of the accompanying model. When it comes to the open character, we took inspiration from open source permissive licenses regarding the grant of IP rights. Referring to the downstream responsible use, we added use-based restrictions not permitting the use of the model in very specific scenarios, in order for the licensor to be able to enforce the license in case potential misuses of the Model may occur. At the same time, we strive to promote open and responsible research on generative models for art and content generation.
|
||||
Even though downstream derivative versions of the model could be released under different licensing terms, the latter will always have to include - at minimum - the same use-based restrictions as the ones in the original license (this license). We believe in the intersection between open and responsible AI development; thus, this agreement aims to strike a balance between both in order to enable responsible open-science in the field of AI.
|
||||
This CreativeML Open RAIL++-M License governs the use of the model (and its derivatives) and is informed by the model card associated with the model.
|
||||
NOW THEREFORE, You and Licensor agree as follows:
|
||||
Definitions
|
||||
"License" means the terms and conditions for use, reproduction, and Distribution as defined in this document.
|
||||
"Data" means a collection of information and/or content extracted from the dataset used with the Model, including to train, pretrain, or otherwise evaluate the Model. The Data is not licensed under this License.
|
||||
"Output" means the results of operating a Model as embodied in informational content resulting therefrom.
|
||||
"Model" means any accompanying machine-learning based assemblies (including checkpoints), consisting of learnt weights, parameters (including optimizer states), corresponding to the model architecture as embodied in the Complementary Material, that have been trained or tuned, in whole or in part on the Data, using the Complementary Material.
|
||||
"Derivatives of the Model" means all modifications to the Model, works based on the Model, or any other model which is created or initialized by transfer of patterns of the weights, parameters, activations or output of the Model, to the other model, in order to cause the other model to perform similarly to the Model, including - but not limited to - distillation methods entailing the use of intermediate data representations or methods based on the generation of synthetic data by the Model for training the other model.
|
||||
"Complementary Material" means the accompanying source code and scripts used to define, run, load, benchmark or evaluate the Model, and used to prepare data for training or evaluation, if any. This includes any accompanying documentation, tutorials, examples, etc, if any.
|
||||
"Distribution" means any transmission, reproduction, publication or other sharing of the Model or Derivatives of the Model to a third party, including providing the Model as a hosted service made available by electronic or other remote means - e.g. API-based or web access.
|
||||
"Licensor" means the copyright owner or entity authorized by the copyright owner that is granting the License, including the persons or entities that may have rights in the Model and/or distributing the Model.
|
||||
"You" (or "Your") means an individual or Legal Entity exercising permissions granted by this License and/or making use of the Model for whichever purpose and in any field of use, including usage of the Model in an end-use application - e.g. chatbot, translator, image generator.
|
||||
"Third Parties" means individuals or legal entities that are not under common control with Licensor or You.
|
||||
"Contribution" means any work of authorship, including the original version of the Model and any modifications or additions to that Model or Derivatives of the Model thereof, that is intentionally submitted to Licensor for inclusion in the Model by the copyright owner or by an individual or Legal Entity authorized to submit on behalf of the copyright owner. For the purposes of this definition, "submitted" means any form of electronic, verbal, or written communication sent to the Licensor or its representatives, including but not limited to communication on electronic mailing lists, source code control systems, and issue tracking systems that are managed by, or on behalf of, the Licensor for the purpose of discussing and improving the Model, but excluding communication that is conspicuously marked or otherwise designated in writing by the copyright owner as "Not a Contribution."
|
||||
"Contributor" means Licensor and any individual or Legal Entity on behalf of whom a Contribution has been received by Licensor and subsequently incorporated within the Model.
|
||||
|
||||
Section II: INTELLECTUAL PROPERTY RIGHTS
|
||||
Both copyright and patent grants apply to the Model, Derivatives of the Model and Complementary Material. The Model and Derivatives of the Model are subject to additional terms as described in
|
||||
|
||||
Section III.
|
||||
Grant of Copyright License. Subject to the terms and conditions of this License, each Contributor hereby grants to You a perpetual, worldwide, non-exclusive, no-charge, royalty-free, irrevocable copyright license to reproduce, prepare, publicly display, publicly perform, sublicense, and distribute the Complementary Material, the Model, and Derivatives of the Model.
|
||||
Grant of Patent License. Subject to the terms and conditions of this License and where and as applicable, each Contributor hereby grants to You a perpetual, worldwide, non-exclusive, no-charge, royalty-free, irrevocable (except as stated in this paragraph) patent license to make, have made, use, offer to sell, sell, import, and otherwise transfer the Model and the Complementary Material, where such license applies only to those patent claims licensable by such Contributor that are necessarily infringed by their Contribution(s) alone or by combination of their Contribution(s) with the Model to which such Contribution(s) was submitted. If You institute patent litigation against any entity (including a cross-claim or counterclaim in a lawsuit) alleging that the Model and/or Complementary Material or a Contribution incorporated within the Model and/or Complementary Material constitutes direct or contributory patent infringement, then any patent licenses granted to You under this License for the Model and/or Work shall terminate as of the date such litigation is asserted or filed.
|
||||
Section III: CONDITIONS OF USAGE, DISTRIBUTION AND REDISTRIBUTION
|
||||
Distribution and Redistribution. You may host for Third Party remote access purposes (e.g. software-as-a-service), reproduce and distribute copies of the Model or Derivatives of the Model thereof in any medium, with or without modifications, provided that You meet the following conditions: Use-based restrictions as referenced in paragraph 5 MUST be included as an enforceable provision by You in any type of legal agreement (e.g. a license) governing the use and/or distribution of the Model or Derivatives of the Model, and You shall give notice to subsequent users You Distribute to, that the Model or Derivatives of the Model are subject to paragraph 5. This provision does not apply to the use of Complementary Material. You must give any Third Party recipients of the Model or Derivatives of the Model a copy of this License; You must cause any modified files to carry prominent notices stating that You changed the files; You must retain all copyright, patent, trademark, and attribution notices excluding those notices that do not pertain to any part of the Model, Derivatives of the Model. You may add Your own copyright statement to Your modifications and may provide additional or different license terms and conditions - respecting paragraph 4.a. - for use, reproduction, or Distribution of Your modifications, or for any such Derivatives of the Model as a whole, provided Your use, reproduction, and Distribution of the Model otherwise complies with the conditions stated in this License.
|
||||
Use-based restrictions. The restrictions set forth in Attachment A are considered Use-based restrictions. Therefore You cannot use the Model and the Derivatives of the Model for the specified restricted uses. You may use the Model subject to this License, including only for lawful purposes and in accordance with the License. Use may include creating any content with, finetuning, updating, running, training, evaluating and/or reparametrizing the Model. You shall require all of Your users who use the Model or a Derivative of the Model to comply with the terms of this paragraph (paragraph 5).
|
||||
The Output You Generate. Except as set forth herein, Licensor claims no rights in the Output You generate using the Model. You are accountable for the Output you generate and its subsequent uses. No use of the output can contravene any provision as stated in the License.
|
||||
|
||||
Section IV: OTHER PROVISIONS
|
||||
Updates and Runtime Restrictions. To the maximum extent permitted by law, Licensor reserves the right to restrict (remotely or otherwise) usage of the Model in violation of this License.
|
||||
Trademarks and related. Nothing in this License permits You to make use of Licensors’ trademarks, trade names, logos or to otherwise suggest endorsement or misrepresent the relationship between the parties; and any rights not expressly granted herein are reserved by the Licensors.
|
||||
Disclaimer of Warranty. Unless required by applicable law or agreed to in writing, Licensor provides the Model and the Complementary Material (and each Contributor provides its Contributions) on an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied, including, without limitation, any warranties or conditions of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A PARTICULAR PURPOSE. You are solely responsible for determining the appropriateness of using or redistributing the Model, Derivatives of the Model, and the Complementary Material and assume any risks associated with Your exercise of permissions under this License.
|
||||
Limitation of Liability. In no event and under no legal theory, whether in tort (including negligence), contract, or otherwise, unless required by applicable law (such as deliberate and grossly negligent acts) or agreed to in writing, shall any Contributor be liable to You for damages, including any direct, indirect, special, incidental, or consequential damages of any character arising as a result of this License or out of the use or inability to use the Model and the Complementary Material (including but not limited to damages for loss of goodwill, work stoppage, computer failure or malfunction, or any and all other commercial damages or losses), even if such Contributor has been advised of the possibility of such damages.
|
||||
Accepting Warranty or Additional Liability. While redistributing the Model, Derivatives of the Model and the Complementary Material thereof, You may choose to offer, and charge a fee for, acceptance of support, warranty, indemnity, or other liability obligations and/or rights consistent with this License. However, in accepting such obligations, You may act only on Your own behalf and on Your sole responsibility, not on behalf of any other Contributor, and only if You agree to indemnify, defend, and hold each Contributor harmless for any liability incurred by, or claims asserted against, such Contributor by reason of your accepting any such warranty or additional liability.
|
||||
If any provision of this License is held to be invalid, illegal or unenforceable, the remaining provisions shall be unaffected thereby and remain valid as if such provision had not been set forth herein.
|
||||
|
||||
END OF TERMS AND CONDITIONS
|
||||
|
||||
Attachment A
|
||||
Use Restrictions
|
||||
You agree not to use the Model or Derivatives of the Model:
|
||||
In any way that violates any applicable national, federal, state, local or international law or regulation;
|
||||
For the purpose of exploiting, harming or attempting to exploit or harm minors in any way;
|
||||
To generate or disseminate verifiably false information and/or content with the purpose of harming others;
|
||||
To generate or disseminate personal identifiable information that can be used to harm an individual;
|
||||
To defame, disparage or otherwise harass others;
|
||||
For fully automated decision making that adversely impacts an individual’s legal rights or otherwise creates or modifies a binding, enforceable obligation;
|
||||
For any use intended to or which has the effect of discriminating against or harming individuals or groups based on online or offline social behavior or known or predicted personal or personality characteristics;
|
||||
To exploit any of the vulnerabilities of a specific group of persons based on their age, social, physical or mental characteristics, in order to materially distort the behavior of a person pertaining to that group in a manner that causes or is likely to cause that person or another person physical or psychological harm;
|
||||
For any use intended to or which has the effect of discriminating against individuals or groups based on legally protected characteristics or categories;
|
||||
To provide medical advice and medical results interpretation;
|
||||
To generate or disseminate information for the purpose to be used for administration of justice, law enforcement, immigration or asylum processes, such as predicting an individual will commit fraud/crime commitment (e.g. by text profiling, drawing causal relationships between assertions made in documents, indiscriminate and arbitrarily-targeted use).
|
||||
|
||||
@@ -0,0 +1,215 @@
|
||||
---
|
||||
license: openrail++
|
||||
tags:
|
||||
- text-to-image
|
||||
- stable-diffusion
|
||||
---
|
||||
# SD-XL 1.0-base Model Card
|
||||

|
||||
|
||||
## Model
|
||||
|
||||

|
||||
|
||||
[SDXL](https://arxiv.org/abs/2307.01952) consists of an [ensemble of experts](https://arxiv.org/abs/2211.01324) pipeline for latent diffusion:
|
||||
In a first step, the base model is used to generate (noisy) latents,
|
||||
which are then further processed with a refinement model (available here: https://huggingface.co/stabilityai/stable-diffusion-xl-refiner-1.0/) specialized for the final denoising steps.
|
||||
Note that the base model can be used as a standalone module.
|
||||
|
||||
Alternatively, we can use a two-stage pipeline as follows:
|
||||
First, the base model is used to generate latents of the desired output size.
|
||||
In the second step, we use a specialized high-resolution model and apply a technique called SDEdit (https://arxiv.org/abs/2108.01073, also known as "img2img")
|
||||
to the latents generated in the first step, using the same prompt. This technique is slightly slower than the first one, as it requires more function evaluations.
|
||||
|
||||
Source code is available at https://github.com/Stability-AI/generative-models .
|
||||
|
||||
### Model Description
|
||||
|
||||
- **Developed by:** Stability AI
|
||||
- **Model type:** Diffusion-based text-to-image generative model
|
||||
- **License:** [CreativeML Open RAIL++-M License](https://huggingface.co/stabilityai/stable-diffusion-xl-base-1.0/blob/main/LICENSE.md)
|
||||
- **Model Description:** This is a model that can be used to generate and modify images based on text prompts. It is a [Latent Diffusion Model](https://arxiv.org/abs/2112.10752) that uses two fixed, pretrained text encoders ([OpenCLIP-ViT/G](https://github.com/mlfoundations/open_clip) and [CLIP-ViT/L](https://github.com/openai/CLIP/tree/main)).
|
||||
- **Resources for more information:** Check out our [GitHub Repository](https://github.com/Stability-AI/generative-models) and the [SDXL report on arXiv](https://arxiv.org/abs/2307.01952).
|
||||
|
||||
### Model Sources
|
||||
|
||||
For research purposes, we recommend our `generative-models` Github repository (https://github.com/Stability-AI/generative-models), which implements the most popular diffusion frameworks (both training and inference) and for which new functionalities like distillation will be added over time.
|
||||
[Clipdrop](https://clipdrop.co/stable-diffusion) provides free SDXL inference.
|
||||
|
||||
- **Repository:** https://github.com/Stability-AI/generative-models
|
||||
- **Demo:** https://clipdrop.co/stable-diffusion
|
||||
|
||||
|
||||
## Evaluation
|
||||

|
||||
The chart above evaluates user preference for SDXL (with and without refinement) over SDXL 0.9 and Stable Diffusion 1.5 and 2.1.
|
||||
The SDXL base model performs significantly better than the previous variants, and the model combined with the refinement module achieves the best overall performance.
|
||||
|
||||
|
||||
### 🧨 Diffusers
|
||||
|
||||
Make sure to upgrade diffusers to >= 0.19.0:
|
||||
```
|
||||
pip install diffusers --upgrade
|
||||
```
|
||||
|
||||
In addition make sure to install `transformers`, `safetensors`, `accelerate` as well as the invisible watermark:
|
||||
```
|
||||
pip install invisible_watermark transformers accelerate safetensors
|
||||
```
|
||||
|
||||
To just use the base model, you can run:
|
||||
|
||||
```py
|
||||
from diffusers import DiffusionPipeline
|
||||
import torch
|
||||
|
||||
pipe = DiffusionPipeline.from_pretrained("stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.float16, use_safetensors=True, variant="fp16")
|
||||
pipe.to("cuda")
|
||||
|
||||
# if using torch < 2.0
|
||||
# pipe.enable_xformers_memory_efficient_attention()
|
||||
|
||||
prompt = "An astronaut riding a green horse"
|
||||
|
||||
images = pipe(prompt=prompt).images[0]
|
||||
```
|
||||
|
||||
To use the whole base + refiner pipeline as an ensemble of experts you can run:
|
||||
|
||||
```py
|
||||
from diffusers import DiffusionPipeline
|
||||
import torch
|
||||
|
||||
# load both base & refiner
|
||||
base = DiffusionPipeline.from_pretrained(
|
||||
"stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.float16, variant="fp16", use_safetensors=True
|
||||
)
|
||||
base.to("cuda")
|
||||
refiner = DiffusionPipeline.from_pretrained(
|
||||
"stabilityai/stable-diffusion-xl-refiner-1.0",
|
||||
text_encoder_2=base.text_encoder_2,
|
||||
vae=base.vae,
|
||||
torch_dtype=torch.float16,
|
||||
use_safetensors=True,
|
||||
variant="fp16",
|
||||
)
|
||||
refiner.to("cuda")
|
||||
|
||||
# Define how many steps and what % of steps to be run on each experts (80/20) here
|
||||
n_steps = 40
|
||||
high_noise_frac = 0.8
|
||||
|
||||
prompt = "A majestic lion jumping from a big stone at night"
|
||||
|
||||
# run both experts
|
||||
image = base(
|
||||
prompt=prompt,
|
||||
num_inference_steps=n_steps,
|
||||
denoising_end=high_noise_frac,
|
||||
output_type="latent",
|
||||
).images
|
||||
image = refiner(
|
||||
prompt=prompt,
|
||||
num_inference_steps=n_steps,
|
||||
denoising_start=high_noise_frac,
|
||||
image=image,
|
||||
).images[0]
|
||||
```
|
||||
|
||||
When using `torch >= 2.0`, you can improve the inference speed by 20-30% with torch.compile. Simple wrap the unet with torch compile before running the pipeline:
|
||||
```py
|
||||
pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True)
|
||||
```
|
||||
|
||||
If you are limited by GPU VRAM, you can enable *cpu offloading* by calling `pipe.enable_model_cpu_offload`
|
||||
instead of `.to("cuda")`:
|
||||
|
||||
```diff
|
||||
- pipe.to("cuda")
|
||||
+ pipe.enable_model_cpu_offload()
|
||||
```
|
||||
|
||||
For more information on how to use Stable Diffusion XL with `diffusers`, please have a look at [the Stable Diffusion XL Docs](https://huggingface.co/docs/diffusers/api/pipelines/stable_diffusion/stable_diffusion_xl).
|
||||
|
||||
### Optimum
|
||||
[Optimum](https://github.com/huggingface/optimum) provides a Stable Diffusion pipeline compatible with both [OpenVINO](https://docs.openvino.ai/latest/index.html) and [ONNX Runtime](https://onnxruntime.ai/).
|
||||
|
||||
#### OpenVINO
|
||||
|
||||
To install Optimum with the dependencies required for OpenVINO :
|
||||
|
||||
```bash
|
||||
pip install optimum[openvino]
|
||||
```
|
||||
|
||||
To load an OpenVINO model and run inference with OpenVINO Runtime, you need to replace `StableDiffusionXLPipeline` with Optimum `OVStableDiffusionXLPipeline`. In case you want to load a PyTorch model and convert it to the OpenVINO format on-the-fly, you can set `export=True`.
|
||||
|
||||
```diff
|
||||
- from diffusers import StableDiffusionXLPipeline
|
||||
+ from optimum.intel import OVStableDiffusionXLPipeline
|
||||
|
||||
model_id = "stabilityai/stable-diffusion-xl-base-1.0"
|
||||
- pipeline = StableDiffusionXLPipeline.from_pretrained(model_id)
|
||||
+ pipeline = OVStableDiffusionXLPipeline.from_pretrained(model_id)
|
||||
prompt = "A majestic lion jumping from a big stone at night"
|
||||
image = pipeline(prompt).images[0]
|
||||
```
|
||||
|
||||
You can find more examples (such as static reshaping and model compilation) in optimum [documentation](https://huggingface.co/docs/optimum/main/en/intel/inference#stable-diffusion-xl).
|
||||
|
||||
|
||||
#### ONNX
|
||||
|
||||
To install Optimum with the dependencies required for ONNX Runtime inference :
|
||||
|
||||
```bash
|
||||
pip install optimum[onnxruntime]
|
||||
```
|
||||
|
||||
To load an ONNX model and run inference with ONNX Runtime, you need to replace `StableDiffusionXLPipeline` with Optimum `ORTStableDiffusionXLPipeline`. In case you want to load a PyTorch model and convert it to the ONNX format on-the-fly, you can set `export=True`.
|
||||
|
||||
```diff
|
||||
- from diffusers import StableDiffusionXLPipeline
|
||||
+ from optimum.onnxruntime import ORTStableDiffusionXLPipeline
|
||||
|
||||
model_id = "stabilityai/stable-diffusion-xl-base-1.0"
|
||||
- pipeline = StableDiffusionXLPipeline.from_pretrained(model_id)
|
||||
+ pipeline = ORTStableDiffusionXLPipeline.from_pretrained(model_id)
|
||||
prompt = "A majestic lion jumping from a big stone at night"
|
||||
image = pipeline(prompt).images[0]
|
||||
```
|
||||
|
||||
You can find more examples in optimum [documentation](https://huggingface.co/docs/optimum/main/en/onnxruntime/usage_guides/models#stable-diffusion-xl).
|
||||
|
||||
|
||||
## Uses
|
||||
|
||||
### Direct Use
|
||||
|
||||
The model is intended for research purposes only. Possible research areas and tasks include
|
||||
|
||||
- Generation of artworks and use in design and other artistic processes.
|
||||
- Applications in educational or creative tools.
|
||||
- Research on generative models.
|
||||
- Safe deployment of models which have the potential to generate harmful content.
|
||||
- Probing and understanding the limitations and biases of generative models.
|
||||
|
||||
Excluded uses are described below.
|
||||
|
||||
### Out-of-Scope Use
|
||||
|
||||
The model was not trained to be factual or true representations of people or events, and therefore using the model to generate such content is out-of-scope for the abilities of this model.
|
||||
|
||||
## Limitations and Bias
|
||||
|
||||
### Limitations
|
||||
|
||||
- The model does not achieve perfect photorealism
|
||||
- The model cannot render legible text
|
||||
- The model struggles with more difficult tasks which involve compositionality, such as rendering an image corresponding to “A red cube on top of a blue sphere”
|
||||
- Faces and people in general may not be generated properly.
|
||||
- The autoencoding part of the model is lossy.
|
||||
|
||||
### Bias
|
||||
While the capabilities of image generation models are impressive, they can also reinforce or exacerbate social biases.
|
||||
@@ -0,0 +1,34 @@
|
||||
{
|
||||
"_class_name": "StableDiffusionXLPipeline",
|
||||
"_diffusers_version": "0.19.0.dev0",
|
||||
"force_zeros_for_empty_prompt": true,
|
||||
"add_watermarker": null,
|
||||
"scheduler": [
|
||||
"diffusers",
|
||||
"EulerDiscreteScheduler"
|
||||
],
|
||||
"text_encoder": [
|
||||
"transformers",
|
||||
"CLIPTextModel"
|
||||
],
|
||||
"text_encoder_2": [
|
||||
"transformers",
|
||||
"CLIPTextModelWithProjection"
|
||||
],
|
||||
"tokenizer": [
|
||||
"transformers",
|
||||
"CLIPTokenizer"
|
||||
],
|
||||
"tokenizer_2": [
|
||||
"transformers",
|
||||
"CLIPTokenizer"
|
||||
],
|
||||
"unet": [
|
||||
"diffusers",
|
||||
"UNet2DConditionModel"
|
||||
],
|
||||
"vae": [
|
||||
"diffusers",
|
||||
"AutoencoderKL"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,18 @@
|
||||
{
|
||||
"_class_name": "EulerDiscreteScheduler",
|
||||
"_diffusers_version": "0.19.0.dev0",
|
||||
"beta_end": 0.012,
|
||||
"beta_schedule": "scaled_linear",
|
||||
"beta_start": 0.00085,
|
||||
"clip_sample": false,
|
||||
"interpolation_type": "linear",
|
||||
"num_train_timesteps": 1000,
|
||||
"prediction_type": "epsilon",
|
||||
"sample_max_value": 1.0,
|
||||
"set_alpha_to_one": false,
|
||||
"skip_prk_steps": true,
|
||||
"steps_offset": 1,
|
||||
"timestep_spacing": "leading",
|
||||
"trained_betas": null,
|
||||
"use_karras_sigmas": false
|
||||
}
|
||||
@@ -0,0 +1,24 @@
|
||||
{
|
||||
"architectures": [
|
||||
"CLIPTextModel"
|
||||
],
|
||||
"attention_dropout": 0.0,
|
||||
"bos_token_id": 0,
|
||||
"dropout": 0.0,
|
||||
"eos_token_id": 2,
|
||||
"hidden_act": "quick_gelu",
|
||||
"hidden_size": 768,
|
||||
"initializer_factor": 1.0,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 3072,
|
||||
"layer_norm_eps": 1e-05,
|
||||
"max_position_embeddings": 77,
|
||||
"model_type": "clip_text_model",
|
||||
"num_attention_heads": 12,
|
||||
"num_hidden_layers": 12,
|
||||
"pad_token_id": 1,
|
||||
"projection_dim": 768,
|
||||
"torch_dtype": "float16",
|
||||
"transformers_version": "4.32.0.dev0",
|
||||
"vocab_size": 49408
|
||||
}
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:ab5cf7327374d8c984f4e963564a329f92c9dad08dac9eee9b8dca86b912f1c9
|
||||
size 1057789
|
||||
@@ -0,0 +1,24 @@
|
||||
{
|
||||
"architectures": [
|
||||
"CLIPTextModelWithProjection"
|
||||
],
|
||||
"attention_dropout": 0.0,
|
||||
"bos_token_id": 0,
|
||||
"dropout": 0.0,
|
||||
"eos_token_id": 2,
|
||||
"hidden_act": "gelu",
|
||||
"hidden_size": 1280,
|
||||
"initializer_factor": 1.0,
|
||||
"initializer_range": 0.02,
|
||||
"intermediate_size": 5120,
|
||||
"layer_norm_eps": 1e-05,
|
||||
"max_position_embeddings": 77,
|
||||
"model_type": "clip_text_model",
|
||||
"num_attention_heads": 20,
|
||||
"num_hidden_layers": 32,
|
||||
"pad_token_id": 1,
|
||||
"projection_dim": 1280,
|
||||
"torch_dtype": "float16",
|
||||
"transformers_version": "4.32.0.dev0",
|
||||
"vocab_size": 49408
|
||||
}
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:38f0a4ff68dd918b24908a264140c2ad0e057eca82616f75c17cbf4a099ad6ad
|
||||
size 2790191
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,24 @@
|
||||
{
|
||||
"bos_token": {
|
||||
"content": "<|startoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"eos_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"pad_token": "<|endoftext|>",
|
||||
"unk_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,33 @@
|
||||
{
|
||||
"add_prefix_space": false,
|
||||
"bos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|startoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"clean_up_tokenization_spaces": true,
|
||||
"do_lower_case": true,
|
||||
"eos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"errors": "replace",
|
||||
"model_max_length": 77,
|
||||
"pad_token": "<|endoftext|>",
|
||||
"tokenizer_class": "CLIPTokenizer",
|
||||
"unk_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
File diff suppressed because it is too large
Load Diff
File diff suppressed because it is too large
Load Diff
+24
@@ -0,0 +1,24 @@
|
||||
{
|
||||
"bos_token": {
|
||||
"content": "<|startoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"eos_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"pad_token": "!",
|
||||
"unk_token": {
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,33 @@
|
||||
{
|
||||
"add_prefix_space": false,
|
||||
"bos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|startoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"clean_up_tokenization_spaces": true,
|
||||
"do_lower_case": true,
|
||||
"eos_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
},
|
||||
"errors": "replace",
|
||||
"model_max_length": 77,
|
||||
"pad_token": "!",
|
||||
"tokenizer_class": "CLIPTokenizer",
|
||||
"unk_token": {
|
||||
"__type": "AddedToken",
|
||||
"content": "<|endoftext|>",
|
||||
"lstrip": false,
|
||||
"normalized": true,
|
||||
"rstrip": false,
|
||||
"single_word": false
|
||||
}
|
||||
}
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,69 @@
|
||||
{
|
||||
"_class_name": "UNet2DConditionModel",
|
||||
"_diffusers_version": "0.19.0.dev0",
|
||||
"act_fn": "silu",
|
||||
"addition_embed_type": "text_time",
|
||||
"addition_embed_type_num_heads": 64,
|
||||
"addition_time_embed_dim": 256,
|
||||
"attention_head_dim": [
|
||||
5,
|
||||
10,
|
||||
20
|
||||
],
|
||||
"block_out_channels": [
|
||||
320,
|
||||
640,
|
||||
1280
|
||||
],
|
||||
"center_input_sample": false,
|
||||
"class_embed_type": null,
|
||||
"class_embeddings_concat": false,
|
||||
"conv_in_kernel": 3,
|
||||
"conv_out_kernel": 3,
|
||||
"cross_attention_dim": 2048,
|
||||
"cross_attention_norm": null,
|
||||
"down_block_types": [
|
||||
"DownBlock2D",
|
||||
"CrossAttnDownBlock2D",
|
||||
"CrossAttnDownBlock2D"
|
||||
],
|
||||
"downsample_padding": 1,
|
||||
"dual_cross_attention": false,
|
||||
"encoder_hid_dim": null,
|
||||
"encoder_hid_dim_type": null,
|
||||
"flip_sin_to_cos": true,
|
||||
"freq_shift": 0,
|
||||
"in_channels": 4,
|
||||
"layers_per_block": 2,
|
||||
"mid_block_only_cross_attention": null,
|
||||
"mid_block_scale_factor": 1,
|
||||
"mid_block_type": "UNetMidBlock2DCrossAttn",
|
||||
"norm_eps": 1e-05,
|
||||
"norm_num_groups": 32,
|
||||
"num_attention_heads": null,
|
||||
"num_class_embeds": null,
|
||||
"only_cross_attention": false,
|
||||
"out_channels": 4,
|
||||
"projection_class_embeddings_input_dim": 2816,
|
||||
"resnet_out_scale_factor": 1.0,
|
||||
"resnet_skip_time_act": false,
|
||||
"resnet_time_scale_shift": "default",
|
||||
"sample_size": 128,
|
||||
"time_cond_proj_dim": null,
|
||||
"time_embedding_act_fn": null,
|
||||
"time_embedding_dim": null,
|
||||
"time_embedding_type": "positional",
|
||||
"timestep_post_act": null,
|
||||
"transformer_layers_per_block": [
|
||||
1,
|
||||
2,
|
||||
10
|
||||
],
|
||||
"up_block_types": [
|
||||
"CrossAttnUpBlock2D",
|
||||
"CrossAttnUpBlock2D",
|
||||
"UpBlock2D"
|
||||
],
|
||||
"upcast_attention": null,
|
||||
"use_linear_projection": true
|
||||
}
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:18955f96dffdba5612c4b554451f4ccc947c93e46df010173791654af4d0d7f6
|
||||
size 22577438
|
||||
@@ -0,0 +1,32 @@
|
||||
{
|
||||
"_class_name": "AutoencoderKL",
|
||||
"_diffusers_version": "0.20.0.dev0",
|
||||
"_name_or_path": "../sdxl-vae/",
|
||||
"act_fn": "silu",
|
||||
"block_out_channels": [
|
||||
128,
|
||||
256,
|
||||
512,
|
||||
512
|
||||
],
|
||||
"down_block_types": [
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D"
|
||||
],
|
||||
"force_upcast": true,
|
||||
"in_channels": 3,
|
||||
"latent_channels": 4,
|
||||
"layers_per_block": 2,
|
||||
"norm_num_groups": 32,
|
||||
"out_channels": 3,
|
||||
"sample_size": 1024,
|
||||
"scaling_factor": 0.13025,
|
||||
"up_block_types": [
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,31 @@
|
||||
{
|
||||
"_class_name": "AutoencoderKL",
|
||||
"_diffusers_version": "0.19.0.dev0",
|
||||
"act_fn": "silu",
|
||||
"block_out_channels": [
|
||||
128,
|
||||
256,
|
||||
512,
|
||||
512
|
||||
],
|
||||
"down_block_types": [
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D"
|
||||
],
|
||||
"force_upcast": true,
|
||||
"in_channels": 3,
|
||||
"latent_channels": 4,
|
||||
"layers_per_block": 2,
|
||||
"norm_num_groups": 32,
|
||||
"out_channels": 3,
|
||||
"sample_size": 1024,
|
||||
"scaling_factor": 0.13025,
|
||||
"up_block_types": [
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:dd61f43e981282b77ecaecf5fc5c842d504932bae78ac99ec581cee50978b423
|
||||
size 992181
|
||||
@@ -0,0 +1,31 @@
|
||||
{
|
||||
"_class_name": "AutoencoderKL",
|
||||
"_diffusers_version": "0.19.0.dev0",
|
||||
"act_fn": "silu",
|
||||
"block_out_channels": [
|
||||
128,
|
||||
256,
|
||||
512,
|
||||
512
|
||||
],
|
||||
"down_block_types": [
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D",
|
||||
"DownEncoderBlock2D"
|
||||
],
|
||||
"force_upcast": true,
|
||||
"in_channels": 3,
|
||||
"latent_channels": 4,
|
||||
"layers_per_block": 2,
|
||||
"norm_num_groups": 32,
|
||||
"out_channels": 3,
|
||||
"sample_size": 1024,
|
||||
"scaling_factor": 0.13025,
|
||||
"up_block_types": [
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D",
|
||||
"UpDecoderBlock2D"
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,3 @@
|
||||
version https://git-lfs.github.com/spec/v1
|
||||
oid sha256:a3ec36b6f3f74d0cb2b005b7c0a1e5426c5ef1e7163b33e463ea57fa049c5996
|
||||
size 849965
|
||||
@@ -0,0 +1,93 @@
|
||||
model:
|
||||
target: sgm.models.diffusion.DiffusionEngine
|
||||
params:
|
||||
scale_factor: 0.13025
|
||||
disable_first_stage_autocast: True
|
||||
|
||||
denoiser_config:
|
||||
target: sgm.modules.diffusionmodules.denoiser.DiscreteDenoiser
|
||||
params:
|
||||
num_idx: 1000
|
||||
|
||||
scaling_config:
|
||||
target: sgm.modules.diffusionmodules.denoiser_scaling.EpsScaling
|
||||
discretization_config:
|
||||
target: sgm.modules.diffusionmodules.discretizer.LegacyDDPMDiscretization
|
||||
|
||||
network_config:
|
||||
target: sgm.modules.diffusionmodules.openaimodel.UNetModel
|
||||
params:
|
||||
adm_in_channels: 2816
|
||||
num_classes: sequential
|
||||
use_checkpoint: True
|
||||
in_channels: 4
|
||||
out_channels: 4
|
||||
model_channels: 320
|
||||
attention_resolutions: [4, 2]
|
||||
num_res_blocks: 2
|
||||
channel_mult: [1, 2, 4]
|
||||
num_head_channels: 64
|
||||
use_linear_in_transformer: True
|
||||
transformer_depth: [1, 2, 10]
|
||||
context_dim: 2048
|
||||
spatial_transformer_attn_type: softmax-xformers
|
||||
|
||||
conditioner_config:
|
||||
target: sgm.modules.GeneralConditioner
|
||||
params:
|
||||
emb_models:
|
||||
- is_trainable: False
|
||||
input_key: txt
|
||||
target: sgm.modules.encoders.modules.FrozenCLIPEmbedder
|
||||
params:
|
||||
layer: hidden
|
||||
layer_idx: 11
|
||||
|
||||
- is_trainable: False
|
||||
input_key: txt
|
||||
target: sgm.modules.encoders.modules.FrozenOpenCLIPEmbedder2
|
||||
params:
|
||||
arch: ViT-bigG-14
|
||||
version: laion2b_s39b_b160k
|
||||
freeze: True
|
||||
layer: penultimate
|
||||
always_return_pooled: True
|
||||
legacy: False
|
||||
|
||||
- is_trainable: False
|
||||
input_key: original_size_as_tuple
|
||||
target: sgm.modules.encoders.modules.ConcatTimestepEmbedderND
|
||||
params:
|
||||
outdim: 256
|
||||
|
||||
- is_trainable: False
|
||||
input_key: crop_coords_top_left
|
||||
target: sgm.modules.encoders.modules.ConcatTimestepEmbedderND
|
||||
params:
|
||||
outdim: 256
|
||||
|
||||
- is_trainable: False
|
||||
input_key: target_size_as_tuple
|
||||
target: sgm.modules.encoders.modules.ConcatTimestepEmbedderND
|
||||
params:
|
||||
outdim: 256
|
||||
|
||||
first_stage_config:
|
||||
target: sgm.models.autoencoder.AutoencoderKL
|
||||
params:
|
||||
embed_dim: 4
|
||||
monitor: val/rec_loss
|
||||
ddconfig:
|
||||
attn_type: vanilla-xformers
|
||||
double_z: true
|
||||
z_channels: 4
|
||||
resolution: 256
|
||||
in_channels: 3
|
||||
out_ch: 3
|
||||
ch: 128
|
||||
ch_mult: [1, 2, 4, 4]
|
||||
num_res_blocks: 2
|
||||
attn_resolutions: []
|
||||
dropout: 0.0
|
||||
lossconfig:
|
||||
target: torch.nn.Identity
|
||||
@@ -0,0 +1,439 @@
|
||||
import os
|
||||
|
||||
os.system("title hook_kohya_ss_run")
|
||||
import random
|
||||
import time
|
||||
|
||||
import torch
|
||||
import logging
|
||||
import sys
|
||||
import json
|
||||
import importlib
|
||||
import argparse
|
||||
import toml
|
||||
|
||||
|
||||
def config2args(train_parser: argparse.ArgumentParser, config):
|
||||
|
||||
config_args_list = []
|
||||
for key, value in config.items():
|
||||
if type(value) == bool:
|
||||
if value:
|
||||
config_args_list.append(f"--{key}")
|
||||
else:
|
||||
config_args_list.append(f"--{key}")
|
||||
config_args_list.append(str(value))
|
||||
args = train_parser.parse_args(config_args_list)
|
||||
return args
|
||||
|
||||
|
||||
from PIL import Image
|
||||
|
||||
|
||||
import numpy as np
|
||||
import tempfile
|
||||
import safetensors.torch
|
||||
|
||||
|
||||
import sys
|
||||
sys.path.append(os.path.dirname(__file__))
|
||||
try:
|
||||
import hook_kohya_ss_utils
|
||||
except:
|
||||
from . import hook_kohya_ss_utils
|
||||
|
||||
other_config = {}
|
||||
original_save_model = None
|
||||
|
||||
|
||||
train_config = {}
|
||||
|
||||
sample_images_pipe_class = None
|
||||
|
||||
|
||||
def utils_sample_images(*args, **kwargs):
|
||||
return sample_images(None, *args, **kwargs)
|
||||
|
||||
|
||||
def get_datasets():
|
||||
import library.config_util
|
||||
user_config = library.config_util.load_user_config(
|
||||
train_config.get("dataset_config", None))
|
||||
datasets = user_config.get("datasets", [])
|
||||
if len(datasets) == 0:
|
||||
return None
|
||||
return datasets[0]
|
||||
|
||||
|
||||
def sample_images(self, *args, **kwargs):
|
||||
# accelerator, args, epoch, global_step, device, vae, tokenizer, text_encoder, unet
|
||||
accelerator = args[0]
|
||||
cmd_args = args[1]
|
||||
epoch = args[2]
|
||||
global_step = args[3]
|
||||
device = args[4]
|
||||
vae = args[5]
|
||||
tokenizer = args[6]
|
||||
text_encoder = args[7]
|
||||
unet = args[8]
|
||||
|
||||
# print(f"sample_images: args = {args}")
|
||||
# print(f"sample_images: kwargs = {kwargs}")
|
||||
|
||||
controlnet = kwargs.get("controlnet", None)
|
||||
|
||||
if epoch is not None and cmd_args.save_every_n_epochs is not None and epoch % cmd_args.save_every_n_epochs == 0:
|
||||
|
||||
datasets = get_datasets()
|
||||
resolution = datasets.get("resolution", (512, 512))
|
||||
if isinstance(resolution, int):
|
||||
resolution = (resolution, resolution)
|
||||
height, width = resolution
|
||||
print(f"sample_images: height = {height}, width = {width}")
|
||||
|
||||
prompt_dict_list = other_config.get("prompt_dict_list", [])
|
||||
if len(prompt_dict_list) == 0:
|
||||
sample_prompt = other_config.get("sample_prompt", None)
|
||||
if sample_prompt is not None:
|
||||
seed = other_config.get("seed", 0)
|
||||
prompt_dict = {
|
||||
"controlnet_image": other_config.get("controlnet_image", None),
|
||||
"prompt": other_config.get("sample_prompt", ""),
|
||||
"seed": seed,
|
||||
"negative_prompt": "",
|
||||
"enum": 0,
|
||||
"sample_sampler": "euler_a",
|
||||
"sample_steps": 20,
|
||||
"scale": 5.0,
|
||||
"height": height,
|
||||
"width": width,
|
||||
}
|
||||
#
|
||||
prompt_dict_list.append(prompt_dict)
|
||||
else:
|
||||
for i, prompt_dict in enumerate(prompt_dict_list):
|
||||
if prompt_dict.get("controlnet_image", None) is None:
|
||||
prompt_dict["controlnet_image"] = None
|
||||
if prompt_dict.get("seed", None) is None:
|
||||
prompt_dict["seed"] = 0
|
||||
if prompt_dict.get("negative_prompt", None) is None:
|
||||
prompt_dict["negative_prompt"] = ""
|
||||
if prompt_dict.get("enum", None) is None:
|
||||
prompt_dict["enum"] = i
|
||||
|
||||
if prompt_dict_list is not None and len(prompt_dict_list) > 0:
|
||||
hook_kohya_ss_utils.generate_image(
|
||||
pipe_class=sample_images_pipe_class,
|
||||
cmd_args=cmd_args,
|
||||
accelerator=accelerator,
|
||||
epoch=epoch,
|
||||
text_encoder=text_encoder,
|
||||
tokenizer=tokenizer,
|
||||
unet=unet,
|
||||
vae=vae,
|
||||
prompt_dict_list=prompt_dict_list,
|
||||
controlnet=controlnet,
|
||||
)
|
||||
|
||||
LOG({
|
||||
"type": "sample_images",
|
||||
"global_step": global_step,
|
||||
"total_steps": cmd_args.max_train_steps,
|
||||
# "latent": noise_pred_latent_path,
|
||||
})
|
||||
|
||||
|
||||
def run_lora_sd1_5():
|
||||
hook_kohya_ss_utils.hook_kohya_ss()
|
||||
|
||||
import train_network
|
||||
train_network.NetworkTrainer.sample_images = sample_images
|
||||
|
||||
import library.train_util
|
||||
global sample_images_pipe_class
|
||||
sample_images_pipe_class = library.train_util.StableDiffusionLongPromptWeightingPipeline
|
||||
|
||||
trainer = train_network.NetworkTrainer()
|
||||
train_args = config2args(train_network.setup_parser(), train_config)
|
||||
|
||||
LOG({
|
||||
"type": "start_train",
|
||||
})
|
||||
trainer.train(train_args)
|
||||
|
||||
|
||||
def run_lora_sdxl():
|
||||
hook_kohya_ss_utils.hook_kohya_ss()
|
||||
|
||||
import sdxl_train_network
|
||||
sdxl_train_network.SdxlNetworkTrainer.sample_images = sample_images
|
||||
|
||||
import library.sdxl_train_util
|
||||
global sample_images_pipe_class
|
||||
sample_images_pipe_class = library.sdxl_train_util.SdxlStableDiffusionLongPromptWeightingPipeline
|
||||
|
||||
trainer = sdxl_train_network.SdxlNetworkTrainer()
|
||||
train_args = config2args(sdxl_train_network.setup_parser(), train_config)
|
||||
|
||||
LOG({
|
||||
"type": "start_train",
|
||||
})
|
||||
trainer.train(train_args)
|
||||
|
||||
|
||||
from types import SimpleNamespace
|
||||
|
||||
|
||||
class SimpleNamespaceCNWarrper(SimpleNamespace):
|
||||
def __init__(self, *args, **kwargs):
|
||||
super().__init__(*args, **kwargs)
|
||||
self.__dict__.update(kwargs) # or self.__dict__ = kwargs
|
||||
self.__dict__["mid_block_type"] = "UNetMidBlock2DCrossAttn"
|
||||
self.__dict__["_diffusers_version"] = "0.6.0"
|
||||
self.__iter__ = lambda: iter(kwargs.keys())
|
||||
# is not iterable
|
||||
|
||||
def __iter__(self):
|
||||
return iter(self.__dict__.keys())
|
||||
# object has no attribute 'num_attention_heads'
|
||||
|
||||
def __getattr__(self, name):
|
||||
return self.__dict__.get(name, None)
|
||||
|
||||
|
||||
def run_controlnet_sd1_5():
|
||||
import types
|
||||
types.SimpleNamespace = SimpleNamespaceCNWarrper
|
||||
hook_kohya_ss_utils.hook_kohya_ss()
|
||||
|
||||
import train_controlnet
|
||||
|
||||
import library.train_util
|
||||
library.train_util.sample_images = utils_sample_images
|
||||
|
||||
global sample_images_pipe_class
|
||||
sample_images_pipe_class = library.train_util.StableDiffusionLongPromptWeightingPipeline
|
||||
|
||||
train_args = config2args(train_controlnet.setup_parser(), train_config)
|
||||
|
||||
LOG({
|
||||
"type": "start_train",
|
||||
})
|
||||
|
||||
train_controlnet.train(train_args)
|
||||
|
||||
|
||||
def run_lora_hunyuan1_2():
|
||||
hook_kohya_ss_utils.hook_kohya_ss()
|
||||
|
||||
import hunyuan_train_network
|
||||
|
||||
hunyuan_train_network.HunYuanNetworkTrainer.sample_images = sample_images
|
||||
|
||||
|
||||
import hook_kohya_ss_hunyuan_pipe
|
||||
global sample_images_pipe_class
|
||||
sample_images_pipe_class = hook_kohya_ss_hunyuan_pipe.HuanYuanDiffusionLongPromptWeightingPipeline
|
||||
import library.hunyuan_utils
|
||||
|
||||
print(json.dumps(other_config, indent=4))
|
||||
hunyuan_models_config = other_config.get("hunyuan_models_config", None)
|
||||
|
||||
from transformers import (
|
||||
AutoTokenizer,
|
||||
T5Tokenizer,
|
||||
BertModel,
|
||||
BertTokenizer,
|
||||
)
|
||||
from diffusers import AutoencoderKL, LMSDiscreteScheduler
|
||||
|
||||
def hunyuan_load_tokenizers():
|
||||
tokenizer = AutoTokenizer.from_pretrained(
|
||||
hunyuan_models_config["tokenizer_path"],
|
||||
local_files_only=True,
|
||||
)
|
||||
tokenizer.eos_token_id = tokenizer.sep_token_id
|
||||
t5_encoder_path = hunyuan_models_config.get("t5_encoder_path", None)
|
||||
if t5_encoder_path == "none":
|
||||
t5_encoder_path = None
|
||||
tokenizer2 = None
|
||||
if t5_encoder_path is not None:
|
||||
tokenizer2 = T5Tokenizer.from_pretrained(
|
||||
t5_encoder_path,
|
||||
local_files_only=True,
|
||||
)
|
||||
|
||||
return [tokenizer, tokenizer2]
|
||||
|
||||
library.hunyuan_utils.load_tokenizers = hunyuan_load_tokenizers
|
||||
|
||||
def hunyuan_load_model(model_path: str, dtype=torch.float16, device="cuda", use_extra_cond=False, dit_path=None):
|
||||
|
||||
dit_path = hunyuan_models_config.get("unet_path", None)
|
||||
|
||||
import library.hunyuan_models
|
||||
MT5Embedder = library.hunyuan_models.MT5Embedder
|
||||
HunYuanDiT = library.hunyuan_models.HunYuanDiT
|
||||
BertModel = library.hunyuan_models.BertModel
|
||||
DiT_g_2 = library.hunyuan_models.DiT_g_2
|
||||
|
||||
denoiser, patch_size, head_dim = DiT_g_2(
|
||||
input_size=(128, 128), use_extra_cond=use_extra_cond)
|
||||
if dit_path is not None:
|
||||
state_dict = torch.load(dit_path)
|
||||
if 'state_dict' in state_dict:
|
||||
state_dict = state_dict['state_dict']
|
||||
else:
|
||||
state_dict = torch.load(os.path.join(
|
||||
model_path, "denoiser/pytorch_model_module.pt"))
|
||||
denoiser.load_state_dict(state_dict)
|
||||
denoiser.to(device).to(dtype)
|
||||
|
||||
clip_tokenizer = AutoTokenizer.from_pretrained(
|
||||
hunyuan_models_config["tokenizer_path"],
|
||||
local_files_only=True,
|
||||
)
|
||||
clip_tokenizer.eos_token_id = 2
|
||||
clip_encoder = (
|
||||
BertModel.from_pretrained(
|
||||
hunyuan_models_config["text_encoder_path"],
|
||||
local_files_only=True,
|
||||
).to(device).to(dtype)
|
||||
)
|
||||
|
||||
t5_encoder_path = hunyuan_models_config.get("t5_encoder_path", None)
|
||||
if t5_encoder_path == "none":
|
||||
t5_encoder_path = None
|
||||
mt5_embedder = None
|
||||
if t5_encoder_path is not None:
|
||||
mt5_embedder = (
|
||||
MT5Embedder(
|
||||
model_dir=hunyuan_models_config["t5_encoder_path"],
|
||||
torch_dtype=dtype,
|
||||
max_length=256)
|
||||
.to(device)
|
||||
.to(dtype)
|
||||
)
|
||||
else:
|
||||
|
||||
batch_size = train_args.train_batch_size
|
||||
import library.config_util
|
||||
user_config = library.config_util.load_user_config(
|
||||
train_args.dataset_config)
|
||||
datasets = user_config.get("datasets", [])
|
||||
if len(datasets) > 0:
|
||||
batch_size = datasets[0].get("batch_size", batch_size)
|
||||
mt5_embedder = (
|
||||
hook_kohya_ss_utils.CustomizeMT5Embedder(
|
||||
batch_size=batch_size,
|
||||
)
|
||||
.to(device)
|
||||
.to(dtype)
|
||||
)
|
||||
|
||||
vae = (
|
||||
AutoencoderKL.from_pretrained(
|
||||
hunyuan_models_config["vae_ema_path"],
|
||||
local_files_only=True,
|
||||
)
|
||||
.to(device)
|
||||
.to(dtype)
|
||||
)
|
||||
vae.requires_grad_(False)
|
||||
return (
|
||||
denoiser,
|
||||
patch_size,
|
||||
head_dim,
|
||||
clip_tokenizer,
|
||||
clip_encoder,
|
||||
mt5_embedder,
|
||||
vae,
|
||||
)
|
||||
|
||||
library.hunyuan_utils.load_model = hunyuan_load_model
|
||||
|
||||
trainer = hunyuan_train_network.HunYuanNetworkTrainer()
|
||||
train_args = config2args(
|
||||
hunyuan_train_network.setup_parser(), train_config)
|
||||
print(f"train_args = {train_args}")
|
||||
|
||||
LOG({
|
||||
"type": "start_train",
|
||||
})
|
||||
trainer.train(train_args)
|
||||
|
||||
|
||||
func_map = {
|
||||
"run_lora_sd1_5": run_lora_sd1_5,
|
||||
"run_lora_sdxl": run_lora_sdxl,
|
||||
"run_controlnet_sd1_5": run_controlnet_sd1_5,
|
||||
"run_lora_hunyuan1_2": run_lora_hunyuan1_2,
|
||||
}
|
||||
|
||||
|
||||
import requests
|
||||
|
||||
|
||||
def LOG(log):
|
||||
try:
|
||||
resp = requests.request("post", f"http://127.0.0.1:{master_port}/log", data=json.dumps(log), headers={
|
||||
"Content-Type": "application/json"})
|
||||
if resp.status_code != 200:
|
||||
# raise Exception(f"LOG failed: {resp.text}")
|
||||
print(f"LOG failed: {resp.text}")
|
||||
except Exception as e:
|
||||
print(f"LOG failed: {e}")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
try:
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--sys_path", type=str, default="")
|
||||
parser.add_argument("--config", type=str, default="")
|
||||
parser.add_argument("--train_func", type=str, default="")
|
||||
parser.add_argument("--master_port", type=int, default=0)
|
||||
args = parser.parse_args()
|
||||
|
||||
master_port = args.master_port
|
||||
|
||||
print(f"master_port = {master_port}")
|
||||
|
||||
sys_path = args.sys_path
|
||||
if sys_path != "":
|
||||
sys.path.append(sys_path)
|
||||
|
||||
config_file = args.config
|
||||
if config_file == "":
|
||||
raise Exception("train_config is empty")
|
||||
|
||||
global_config = {}
|
||||
with open(config_file, "r") as f:
|
||||
_global_config = f.read()
|
||||
global_config = json.loads(_global_config)
|
||||
|
||||
train_config = global_config.get("train_config")
|
||||
print(f"""=======================train_config=======================
|
||||
{json.dumps(train_config, indent=4, ensure_ascii=False)}
|
||||
""")
|
||||
|
||||
other_config = global_config.get("other_config", {})
|
||||
print(f"""=======================other_config=======================
|
||||
{json.dumps(other_config, indent=4, ensure_ascii=False)}
|
||||
""")
|
||||
|
||||
train_func = args.train_func
|
||||
if train_func == "":
|
||||
raise Exception("train_func is empty")
|
||||
|
||||
print(f"train_func = {train_func}")
|
||||
|
||||
time.sleep(2)
|
||||
LOG({
|
||||
"type": "Read configuration completed!",
|
||||
})
|
||||
|
||||
func_map[train_func]()
|
||||
except Exception as e:
|
||||
print(f"Exception: {e}")
|
||||
if sys.platform == "win32":
|
||||
input("Press Enter to continue...")
|
||||
@@ -0,0 +1,606 @@
|
||||
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import os
|
||||
from typing import *
|
||||
import torch
|
||||
from diffusers import StableDiffusionPipeline, StableDiffusionXLPipeline
|
||||
from transformers import CLIPTokenizer
|
||||
import requests
|
||||
|
||||
_requests_get = requests.get
|
||||
|
||||
source_replacement_table = {
|
||||
"https://raw.githubusercontent.com/CompVis/stable-diffusion/main/configs/stable-diffusion/v1-inference.yaml": os.path.join(
|
||||
os.path.dirname(__file__), "configs", "models_config", "stable-diffusion-v1.5", "v1-inference.yaml"),
|
||||
"https://raw.githubusercontent.com/Stability-AI/generative-models/main/configs/inference/sd_xl_base.yaml": os.path.join(
|
||||
os.path.dirname(__file__), "configs", "models_config", "stable-diffusion-xl", "sd_xl_base.yaml"),
|
||||
"https://huggingface.co/openai/clip-vit-large-patch14/resolve/main/tokenizer_config.json": os.path.join(
|
||||
os.path.dirname(__file__), "configs", "models_config", "clip-vit-large-patch14", "tokenizer_config.json"),
|
||||
"https://huggingface.co/api/models/stabilityai/stable-diffusion-3-medium-diffusers/revision/main": os.path.join(
|
||||
os.path.dirname(__file__), "configs", "models_config", "stable-diffusion-3-medium-diffusers", "revision.json"),
|
||||
}
|
||||
|
||||
source_replacement_dir = {
|
||||
"https://huggingface.co/stabilityai/stable-diffusion-3-medium-diffusers/resolve/b1148b4028b9ec56ebd36444c193d56aeff7ab56": os.path.join(
|
||||
os.path.dirname(__file__), "configs", "models_config", "stable-diffusion-3-medium-diffusers"),
|
||||
}
|
||||
|
||||
|
||||
class DictWrapper:
|
||||
def __init__(self, d):
|
||||
self.d = d
|
||||
|
||||
def __getattribute__(self, name: str):
|
||||
if name == "content":
|
||||
return self.d["content"]
|
||||
if name == "raise_for_status":
|
||||
return lambda: None
|
||||
if name == "json":
|
||||
return lambda: json.loads(self.d["content"])
|
||||
if name == "status_code":
|
||||
return self.d["status_code"]
|
||||
if name == "headers":
|
||||
return {
|
||||
"Location": self.d["Location"],
|
||||
"Content-Length": len(self.d["content"]),
|
||||
}
|
||||
if name == "request":
|
||||
return None
|
||||
return super().__getattribute__(name)
|
||||
|
||||
|
||||
def request_wrapper(*args, **kwargs):
|
||||
url = args[1]
|
||||
print(f"request_wrapper requesting {url}")
|
||||
if url in source_replacement_table:
|
||||
with open(source_replacement_table[url], "rb") as f:
|
||||
return DictWrapper({
|
||||
"Location": url,
|
||||
"content": f.read(),
|
||||
"status_code": 200,
|
||||
})
|
||||
|
||||
print(f"request_wrapper requesting {url} from original requests")
|
||||
return _requests_get(*args, **kwargs)
|
||||
|
||||
|
||||
from requests import api
|
||||
from requests import Session
|
||||
last_request = api.request
|
||||
original_session_request = Session.request
|
||||
api.request = request_wrapper
|
||||
|
||||
|
||||
def Session_request_wrapper(cls, method, url, **kwargs):
|
||||
if url.startswith("http://127.0.0.1"):
|
||||
return original_session_request(cls, method, url, **kwargs)
|
||||
# print(f"Session_request_wrapper requesting {url}")
|
||||
# print(f"Session_request_wrapper requesting kwargs: {kwargs}")
|
||||
if url in source_replacement_table:
|
||||
with open(source_replacement_table[url], "rb") as f:
|
||||
return DictWrapper({
|
||||
"Location": url,
|
||||
"content": f.read(),
|
||||
"status_code": 200,
|
||||
})
|
||||
|
||||
for k, v in source_replacement_dir.items():
|
||||
if url.startswith(k):
|
||||
file_path = source_replacement_dir[k] + url[len(k):]
|
||||
# print(
|
||||
# f"source_replacement_dir:{k}||||||||||||||||||||| {source_replacement_dir[k]} ||||||||||||||||||| {file_path}")
|
||||
with open(file_path, "rb") as f:
|
||||
return DictWrapper({
|
||||
"Location": url,
|
||||
"content": f.read(),
|
||||
"status_code": 200,
|
||||
})
|
||||
raise NotImplementedError("Session.request is not supported")
|
||||
|
||||
|
||||
Session.request = Session_request_wrapper
|
||||
|
||||
import huggingface_hub.file_download
|
||||
|
||||
|
||||
def _hf_hub_download_to_cache_dir(repo_id, filename, *args, **kwargs):
|
||||
print(f"_hf_hub_download_to_cache_dir: {args}")
|
||||
print(f"_hf_hub_download_to_cache_dir: {kwargs}")
|
||||
if repo_id == "stabilityai/stable-diffusion-3-medium-diffusers":
|
||||
return os.path.join(
|
||||
os.path.dirname(__file__), "configs", "models_config", "stable-diffusion-3-medium-diffusers", filename)
|
||||
raise NotImplementedError("_hf_hub_download_to_cache_dir is not supported")
|
||||
|
||||
|
||||
huggingface_hub.file_download._hf_hub_download_to_cache_dir = _hf_hub_download_to_cache_dir
|
||||
|
||||
import diffusers.loaders.single_file
|
||||
original_snapshot_download = diffusers.loaders.single_file.snapshot_download
|
||||
|
||||
|
||||
def _snapshot_download(repo_id, *args, **kwargs):
|
||||
print(f"_snapshot_download: {repo_id}")
|
||||
if repo_id == "stabilityai/stable-diffusion-3-medium-diffusers":
|
||||
return os.path.join(
|
||||
os.path.dirname(__file__), "configs", "models_config", "stable-diffusion-3-medium-diffusers",)
|
||||
if repo_id == "runwayml/stable-diffusion-v1-5":
|
||||
return os.path.join(
|
||||
os.path.dirname(__file__), "configs", "models_config", "stable-diffusion-v1-5",)
|
||||
if repo_id == "stabilityai/stable-diffusion-xl-base-1.0":
|
||||
return os.path.join(
|
||||
os.path.dirname(__file__), "configs", "models_config", "stable-diffusion-xl-base-1.0",)
|
||||
# return original_snapshot_download(repo_id, *args, **kwargs)
|
||||
raise NotImplementedError("_snapshot_download is not supported")
|
||||
|
||||
|
||||
diffusers.loaders.single_file.snapshot_download = _snapshot_download
|
||||
|
||||
original_load_target_model = None
|
||||
|
||||
|
||||
def setup_logging(*args, **kwargs):
|
||||
pass
|
||||
|
||||
|
||||
clip_large_tokenizer = None
|
||||
clip_big_tokenizer = None
|
||||
|
||||
|
||||
class TokenizersWrapper:
|
||||
typed = None
|
||||
model_max_length = 77
|
||||
|
||||
def __init__(self, t):
|
||||
self.model_max_length = 77
|
||||
self.typed = t
|
||||
|
||||
def __getattribute__(self, name: str):
|
||||
# print(f"TokenizersWrapper.__getattribute__ {name}")
|
||||
if name == "model_max_length":
|
||||
return 77
|
||||
try:
|
||||
typed = object.__getattribute__(self, "typed")
|
||||
if typed == "clip_large" and clip_large_tokenizer is not None:
|
||||
return clip_large_tokenizer.__getattribute__(name)
|
||||
if typed == "clip_big" and clip_big_tokenizer is not None:
|
||||
return clip_big_tokenizer.__getattribute__(name)
|
||||
except:
|
||||
pass
|
||||
|
||||
return object.__getattribute__(self, name)
|
||||
|
||||
def __call__(self, *args, **kargs):
|
||||
if self.typed == "clip_large":
|
||||
return clip_large_tokenizer(*args, **kargs)
|
||||
if self.typed == "clip_big":
|
||||
return clip_big_tokenizer(*args, **kargs)
|
||||
|
||||
raise NotImplementedError(
|
||||
f"TokenizersWrapper: {self.typed} is not supported")
|
||||
|
||||
|
||||
from transformers import AutoTokenizer, MT5EncoderModel
|
||||
from torch import nn
|
||||
|
||||
|
||||
class CustomizeEmbedsModel(nn.Module):
|
||||
dtype = torch.float16
|
||||
shared = None
|
||||
# x = torch.zeros(1, 1, 256, 2048)
|
||||
x = None
|
||||
|
||||
def __init__(self, *args, **kwargs):
|
||||
super().__init__()
|
||||
|
||||
def to(self, *args, **kwargs):
|
||||
return self
|
||||
|
||||
def forward(self, *args, **kwargs):
|
||||
# print("CustomizeEmbedsModel forward: args:", args)
|
||||
# print("CustomizeEmbedsModel forward: kwargs:", kwargs)
|
||||
input_ids = kwargs.get("input_ids", None)
|
||||
# if self.x is None:
|
||||
if True:
|
||||
if input_ids is None:
|
||||
batch_size = 1
|
||||
else:
|
||||
batch_size = input_ids.shape[0]
|
||||
|
||||
attention_mask = kwargs.get("attention_mask")
|
||||
attention_mask_dim = attention_mask.shape[1]
|
||||
self.x = torch.zeros(1, batch_size, 256, 2048, dtype=self.dtype)
|
||||
|
||||
if kwargs.get("output_hidden_states", False):
|
||||
return {
|
||||
"hidden_states": self.x.to("cuda"),
|
||||
"input_ids": torch.zeros(1, 1),
|
||||
}
|
||||
return self.x
|
||||
|
||||
|
||||
class CustomizeTokenizer(dict):
|
||||
added_tokens_encoder = []
|
||||
input_ids = None
|
||||
attention_mask = None
|
||||
batch_size = 1
|
||||
|
||||
def __init__(self, *args, **kwargs):
|
||||
self['added_tokens_encoder'] = self.added_tokens_encoder
|
||||
self['input_ids'] = self.input_ids
|
||||
self['attention_mask'] = self.attention_mask
|
||||
self.batch_size = kwargs.get("batch_size", 1)
|
||||
|
||||
def tokenize(self, text):
|
||||
return text
|
||||
|
||||
def __call__(self, *args, **kwargs):
|
||||
# print("CustomizeTokenizer args:", args)
|
||||
# print("CustomizeTokenizer kwargs:", kwargs)
|
||||
|
||||
value = args[0]
|
||||
if isinstance(value, str):
|
||||
batch_size = 1
|
||||
else:
|
||||
batch_size = value.shape[0]
|
||||
|
||||
# print(f"CustomizeTokenizer batch_size: {batch_size}")
|
||||
# if self.input_ids is not None:
|
||||
# return self
|
||||
|
||||
self.input_ids = torch.zeros(batch_size, 256)
|
||||
self.attention_mask = torch.zeros(batch_size, 256)
|
||||
self['input_ids'] = self.input_ids
|
||||
self['attention_mask'] = self.attention_mask
|
||||
|
||||
# print("CustomizeTokenizer input_ids:", self.input_ids.shape)
|
||||
# print("CustomizeTokenizer attention_mask:", self.attention_mask.shape)
|
||||
|
||||
return self
|
||||
|
||||
|
||||
class CustomizeEmbeds():
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.tokenizer = CustomizeTokenizer()
|
||||
self.model = CustomizeEmbedsModel().to("cuda")
|
||||
self.max_length = 256
|
||||
|
||||
|
||||
class CustomizeMT5Embedder(nn.Module):
|
||||
device = torch.device("cuda")
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
model_dir="t5-v1_1-xxl",
|
||||
model_kwargs=None,
|
||||
torch_dtype=None,
|
||||
use_tokenizer_only=False,
|
||||
max_length=128,
|
||||
batch_size=1,
|
||||
):
|
||||
super().__init__()
|
||||
self.torch_dtype = torch_dtype or torch.bfloat16
|
||||
self.max_length = max_length
|
||||
self.tokenizer = CustomizeTokenizer(
|
||||
batch_size=batch_size
|
||||
)
|
||||
self.model = CustomizeEmbedsModel().to("cuda")
|
||||
|
||||
def gradient_checkpointing_enable(self):
|
||||
pass
|
||||
|
||||
def gradient_checkpointing_disable(self):
|
||||
pass
|
||||
|
||||
def get_tokens_and_mask(self, texts):
|
||||
text_tokens_and_mask = self.tokenizer(
|
||||
texts,
|
||||
max_length=self.max_length,
|
||||
padding="max_length",
|
||||
truncation=True,
|
||||
return_attention_mask=True,
|
||||
add_special_tokens=True,
|
||||
return_tensors="pt",
|
||||
)
|
||||
tokens = text_tokens_and_mask["input_ids"][0]
|
||||
mask = text_tokens_and_mask["attention_mask"][0]
|
||||
return tokens, mask
|
||||
|
||||
def get_text_embeddings(self, texts, attention_mask=True, layer_index=-1):
|
||||
text_tokens_and_mask = self.tokenizer(
|
||||
texts,
|
||||
max_length=self.max_length,
|
||||
padding="max_length",
|
||||
truncation=True,
|
||||
return_attention_mask=True,
|
||||
add_special_tokens=True,
|
||||
return_tensors="pt",
|
||||
)
|
||||
|
||||
outputs = self.model(
|
||||
input_ids=text_tokens_and_mask["input_ids"],
|
||||
attention_mask=(
|
||||
text_tokens_and_mask["attention_mask"]
|
||||
if attention_mask
|
||||
else None
|
||||
),
|
||||
output_hidden_states=True,
|
||||
)
|
||||
text_encoder_embs = outputs["hidden_states"][layer_index].detach()
|
||||
|
||||
return text_encoder_embs, text_tokens_and_mask["attention_mask"].to(self.device)
|
||||
|
||||
def get_input_ids(self, caption):
|
||||
return self.tokenizer(
|
||||
caption,
|
||||
padding="max_length",
|
||||
truncation=True,
|
||||
max_length=self.max_length,
|
||||
return_tensors="pt",
|
||||
).input_ids
|
||||
|
||||
def get_hidden_states(self, input_ids, layer_index=-1):
|
||||
return self.get_text_embeddings(input_ids, layer_index=layer_index)
|
||||
|
||||
|
||||
def load_tokenizers(*args, **kwargs):
|
||||
return TokenizersWrapper("clip_large")
|
||||
|
||||
|
||||
def load_sdxl_tokenizers(*args, **kwargs):
|
||||
return [TokenizersWrapper("clip_large"), TokenizersWrapper("clip_big")]
|
||||
|
||||
|
||||
original_conditional_loss = None
|
||||
|
||||
|
||||
running_info = {}
|
||||
|
||||
|
||||
def conditional_loss(*args, **kwargs):
|
||||
running_info["last_noise_pred"] = args[0]
|
||||
return original_conditional_loss(*args, **kwargs)
|
||||
|
||||
|
||||
def decode_latents(vae, latents):
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
latents = latents.to(dtype=vae.dtype).to(device)
|
||||
vae = vae.to(device)
|
||||
latents = 1 / 0.18215 * latents
|
||||
image = vae.decode(latents).sample
|
||||
image = (image / 2 + 0.5).clamp(0, 1)
|
||||
# we always cast to float32 as this does not cause significant overhead and is compatible with bfloat16
|
||||
image = image.cpu().permute(0, 2, 3, 1).float().detach().numpy()
|
||||
return image
|
||||
|
||||
|
||||
def hook_kohya_ss():
|
||||
import library.utils
|
||||
import library.train_util
|
||||
import library.sdxl_train_util
|
||||
library.utils.setup_logging = setup_logging
|
||||
|
||||
library.train_util.load_tokenizer = load_tokenizers
|
||||
library.sdxl_train_util.load_tokenizers = load_sdxl_tokenizers
|
||||
|
||||
global original_load_target_model
|
||||
if original_load_target_model is None:
|
||||
original_load_target_model = library.train_util._load_target_model
|
||||
|
||||
library.train_util._load_target_model = _load_target_model
|
||||
|
||||
library.sdxl_train_util._load_target_model = _sdxl_load_target_model
|
||||
|
||||
global original_conditional_loss
|
||||
if original_conditional_loss is None:
|
||||
original_conditional_loss = library.train_util.conditional_loss
|
||||
library.train_util.conditional_loss = conditional_loss
|
||||
|
||||
|
||||
def _sdxl_load_target_model(
|
||||
name_or_path: str, vae_path: Optional[str], model_version: str, weight_dtype, device="cpu", model_dtype=None, *args, **kwargs
|
||||
):
|
||||
import library.sdxl_model_util as sdxl_model_util
|
||||
import library.model_util as model_util
|
||||
import library.sdxl_original_unet as sdxl_original_unet
|
||||
import library.sdxl_train_util
|
||||
init_empty_weights = library.sdxl_train_util.init_empty_weights
|
||||
|
||||
# model_dtype only work with full fp16/bf16
|
||||
name_or_path = os.readlink(name_or_path) if os.path.islink(
|
||||
name_or_path) else name_or_path
|
||||
load_stable_diffusion_format = False
|
||||
|
||||
if True:
|
||||
# Diffusers model is loaded to CPU
|
||||
variant = "fp16" if weight_dtype == torch.float16 else None
|
||||
print(
|
||||
f"load Diffusers pretrained models: {name_or_path}, variant={variant}")
|
||||
try:
|
||||
try:
|
||||
pipe = StableDiffusionXLPipeline.from_single_file(
|
||||
name_or_path, local_files_only=True, safety_checker=None)
|
||||
except EnvironmentError as ex:
|
||||
raise ex
|
||||
except EnvironmentError as ex:
|
||||
print(
|
||||
f"model is not found as a file or in Hugging Face, perhaps file name is wrong? / 指定したモデル名のファイル、またはHugging Faceのモデルが見つかりません。ファイル名が誤っているかもしれません: {name_or_path}"
|
||||
)
|
||||
raise ex
|
||||
|
||||
text_encoder1 = pipe.text_encoder
|
||||
text_encoder2 = pipe.text_encoder_2
|
||||
|
||||
# convert to fp32 for cache text_encoders outputs
|
||||
if text_encoder1.dtype != torch.float32:
|
||||
text_encoder1 = text_encoder1.to(dtype=torch.float32)
|
||||
if text_encoder2.dtype != torch.float32:
|
||||
text_encoder2 = text_encoder2.to(dtype=torch.float32)
|
||||
|
||||
vae = pipe.vae
|
||||
unet = pipe.unet
|
||||
global clip_large_tokenizer, clip_big_tokenizer
|
||||
clip_large_tokenizer = pipe.tokenizer
|
||||
clip_big_tokenizer = pipe.tokenizer_2
|
||||
del pipe
|
||||
|
||||
# Diffusers U-Net to original U-Net
|
||||
state_dict = sdxl_model_util.convert_diffusers_unet_state_dict_to_sdxl(
|
||||
unet.state_dict())
|
||||
with init_empty_weights():
|
||||
unet = sdxl_original_unet.SdxlUNet2DConditionModel() # overwrite unet
|
||||
sdxl_model_util._load_state_dict_on_device(
|
||||
unet, state_dict, device=device, dtype=model_dtype)
|
||||
print("U-Net converted to original U-Net")
|
||||
|
||||
logit_scale = None
|
||||
ckpt_info = None
|
||||
|
||||
# VAEを読み込む
|
||||
if vae_path is not None:
|
||||
vae = model_util.load_vae(vae_path, weight_dtype)
|
||||
print("additional VAE loaded")
|
||||
|
||||
return load_stable_diffusion_format, text_encoder1, text_encoder2, vae, unet, logit_scale, ckpt_info
|
||||
|
||||
|
||||
def _load_target_model(args: argparse.Namespace, weight_dtype, device="cpu", unet_use_linear_projection_in_v2=False):
|
||||
import library.model_util as model_util
|
||||
from library.original_unet import UNet2DConditionModel
|
||||
|
||||
name_or_path = args.pretrained_model_name_or_path
|
||||
name_or_path = os.path.realpath(name_or_path) if os.path.islink(
|
||||
name_or_path) else name_or_path
|
||||
load_stable_diffusion_format = False
|
||||
if True:
|
||||
# Diffusers model is loaded to CPU
|
||||
try:
|
||||
pipe = StableDiffusionPipeline.from_single_file(
|
||||
name_or_path, local_files_only=True, safety_checker=None)
|
||||
except EnvironmentError as ex:
|
||||
print(
|
||||
f"model is not found as a file or in Hugging Face, perhaps file name is wrong? / 指定したモデル名のファイル、またはHugging Faceのモデルが見つかりません。ファイル名が誤っているかもしれません: {name_or_path}"
|
||||
)
|
||||
raise ex
|
||||
|
||||
text_encoder = pipe.text_encoder
|
||||
vae = pipe.vae
|
||||
unet = pipe.unet
|
||||
global clip_large_tokenizer
|
||||
clip_large_tokenizer = pipe.tokenizer
|
||||
del pipe
|
||||
|
||||
# Diffusers U-Net to original U-Net
|
||||
# TODO *.ckpt/*.safetensorsのv2と同じ形式にここで変換すると良さそう
|
||||
# print(f"unet config: {unet.config}")
|
||||
original_unet = UNet2DConditionModel(
|
||||
unet.config.sample_size,
|
||||
unet.config.attention_head_dim,
|
||||
unet.config.cross_attention_dim,
|
||||
unet.config.use_linear_projection,
|
||||
unet.config.upcast_attention,
|
||||
)
|
||||
original_unet.load_state_dict(unet.state_dict())
|
||||
unet = original_unet
|
||||
print("U-Net converted to original U-Net")
|
||||
|
||||
# VAEを読み込む
|
||||
if args.vae is not None:
|
||||
vae = model_util.load_vae(args.vae, weight_dtype)
|
||||
print("additional VAE loaded")
|
||||
|
||||
return text_encoder, vae, unet, load_stable_diffusion_format
|
||||
|
||||
|
||||
def generate_image(pipe_class, cmd_args, accelerator, vae, tokenizer, text_encoder, unet, epoch, prompt_dict_list, **kwargs):
|
||||
if pipe_class is None:
|
||||
print("pipe_class is None")
|
||||
return
|
||||
import library.train_util
|
||||
|
||||
# for multi gpu distributed inference. this is a singleton, so it's safe to use it here
|
||||
distributed_state = library.train_util.PartialState()
|
||||
org_vae_device = vae.device # CPU
|
||||
vae.to(distributed_state.device)
|
||||
unet = accelerator.unwrap_model(unet)
|
||||
|
||||
if isinstance(text_encoder, (list, tuple)):
|
||||
text_encoder = [accelerator.unwrap_model(te) for te in text_encoder]
|
||||
else:
|
||||
text_encoder = accelerator.unwrap_model(text_encoder)
|
||||
|
||||
default_scheduler = library.train_util.get_my_scheduler(
|
||||
sample_sampler="k_euler",
|
||||
v_parameterization=cmd_args.v_parameterization,
|
||||
)
|
||||
|
||||
pipeline = pipe_class(
|
||||
text_encoder=text_encoder,
|
||||
vae=vae,
|
||||
unet=unet,
|
||||
tokenizer=tokenizer,
|
||||
scheduler=default_scheduler,
|
||||
safety_checker=None,
|
||||
feature_extractor=None,
|
||||
requires_safety_checker=False,
|
||||
clip_skip=cmd_args.clip_skip,
|
||||
)
|
||||
pipeline.to(distributed_state.device)
|
||||
|
||||
workspaces_dir = os.path.dirname(cmd_args.dataset_config)
|
||||
sample_images_path = os.path.join(
|
||||
workspaces_dir, "sample_images")
|
||||
|
||||
os.makedirs(sample_images_path, exist_ok=True)
|
||||
|
||||
lora_output_name = cmd_args.output_name
|
||||
|
||||
save_dir = sample_images_path
|
||||
prompt_replacement = None
|
||||
steps = 0
|
||||
controlnet = None
|
||||
|
||||
# save random state to restore later
|
||||
rng_state = torch.get_rng_state()
|
||||
cuda_rng_state = None
|
||||
try:
|
||||
cuda_rng_state = torch.cuda.get_rng_state() if torch.cuda.is_available() else None
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
image_counter = 0
|
||||
|
||||
with torch.no_grad():
|
||||
for prompt_dict in prompt_dict_list:
|
||||
# Generate the custom image name
|
||||
if image_counter == 0:
|
||||
custom_name = "Sanity Check"
|
||||
else:
|
||||
custom_name = f"Epoch {image_counter}"
|
||||
|
||||
# Call sample_image_inference
|
||||
library.train_util.sample_image_inference(
|
||||
accelerator, cmd_args, pipeline, save_dir, prompt_dict, epoch, steps, prompt_replacement,
|
||||
controlnet=controlnet
|
||||
)
|
||||
|
||||
# Rename the generated image
|
||||
old_name = f"{cmd_args.output_name}_{epoch:06d}-{steps:06d}_{prompt_dict.get('seed', 0)}.png"
|
||||
new_name = f"{custom_name}_{prompt_dict.get('seed', 0)}.png"
|
||||
old_path = os.path.join(save_dir, old_name)
|
||||
new_path = os.path.join(save_dir, new_name)
|
||||
|
||||
if os.path.exists(old_path):
|
||||
os.rename(old_path, new_path)
|
||||
|
||||
image_counter += 1
|
||||
|
||||
del pipeline
|
||||
library.train_util.clean_memory_on_device(accelerator.device)
|
||||
|
||||
torch.set_rng_state(rng_state)
|
||||
if cuda_rng_state is not None:
|
||||
torch.cuda.set_rng_state(cuda_rng_state)
|
||||
vae.to(org_vae_device)
|
||||
@@ -0,0 +1,15 @@
|
||||
import { app } from "../../scripts/app.js";
|
||||
|
||||
app.registerExtension({
|
||||
name: "Fill-Nodes.appearance", // Extension name
|
||||
async nodeCreated(node) {
|
||||
// Check if the node's comfyClass starts with "FL_"
|
||||
if (node.comfyClass.startsWith("FL_")) {
|
||||
// Apply styling
|
||||
node.color = "#16727c";
|
||||
node.bgcolor = "#4F0074";
|
||||
|
||||
|
||||
}
|
||||
}
|
||||
});
|
||||
Reference in New Issue
Block a user