Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Gökay Aydoğan |
0cb9dabc88 | ||
|
Gökay Aydoğan
|
a3f0cdb50c | ||
|
Gökay Aydoğan
|
dbca7c5c71 | ||
|
gokayfem
|
821dc30d62 | ||
|
gokayfem
|
0184abc000 | ||
|
gokayfem
|
908c7f4bbe | ||
|
gokayfem
|
c9a891ca23 | ||
|
gokayfem
|
321caeaf4f | ||
|
gokayfem
|
69c93cdd13 | ||
|
gokayfem
|
15822ab792 | ||
|
gokayfem
|
cbb521c2d8 | ||
|
gokayfem
|
5779fbb711 | ||
|
gokayfem
|
294a6e3df0 | ||
|
gokayfem
|
1bf3cfadab | ||
|
gokayfem
|
97271dca25 | ||
|
gokayfem
|
2bd701d592 | ||
|
gokayfem
|
003e9fa78d | ||
|
gokayfem
|
15bc6a5c82 | ||
|
gokayfem
|
2ae16345c1 | ||
|
gokayfem
|
2c541bd3c6 | ||
|
gokayfem
|
f029a1b4ae | ||
|
gokayfem
|
b05447d8dc | ||
|
gokayfem
|
3de4a87b5d | ||
|
gokayfem
|
1ed7325d48 | ||
|
gokayfem
|
4f4873dc19 | ||
|
gokayfem
|
a92d314348 | ||
|
gokayfem
|
d65f929d0b | ||
|
gokayfem
|
51a1f7c442 | ||
|
gokayfem
|
454525c2ee | ||
|
gokayfem
|
d6f917052c | ||
|
gokayfem
|
acfe70d4fa | ||
|
gokayfem
|
8eb3c5a756 |
@@ -8,10 +8,13 @@
|
||||
<br/>
|
||||
|
||||
## Usage
|
||||
- For **Windows** and **Linux**
|
||||
```
|
||||
cd custom_nodes
|
||||
git clone https://github.com/gokayfem/ComfyUI_VLM_nodes.git
|
||||
```
|
||||
- For **macOS** go to the ```mac``` branch. Download the repository as zip and unzip it to the ```custom_nodes``` folder.
|
||||
|
||||
## VLM Nodes
|
||||
Utilizes ```llama-cpp-python``` for integration of LLaVa models. You can load and use any VLM with LLaVa models in GGUF format with this nodes.
|
||||
You need to download the model similar to ```ggml-model-q4_k.gguf``` and it's clip projector similar to ```mmproj-model-f16.gguf``` from this repositories (in the files and versions).
|
||||
@@ -24,17 +27,12 @@ Note that every **model's clip projector** is different!
|
||||
- [LlaVa 1.5 13B](https://huggingface.co/mys/ggml_llava-v1.5-13b)
|
||||
- [BakLLaVa](https://huggingface.co/mys/ggml_bakllava-1)
|
||||
etc..
|
||||
## InternLM-XComposer2-VL Node
|
||||
Utilizes ```AutoGPTQ``` for integration of InternLM-XComposer2-VL Model. It will automatically download the necessary files into ```custom_nodes/ComfyUI_VLM_nodes/nodes/files_for_internlm```.
|
||||
This is one of the best models for visual perception.
|
||||
**Important Note : This model is heavy.**
|
||||
- [InternLM-XComposer2](https://huggingface.co/internlm/internlm-xcomposer2-vl-7b-4bit)
|
||||
|
||||
## Automatic Prompt Generation and Suggestion Nodes
|
||||
**Get Keyword** node: It can take LLava outputs and extract keywords from them.
|
||||
**LLava PromptGenerator** node: It can create prompts given descriptions or keywords using (input prompt could be Get Keyword or LLava output directly).
|
||||
**Suggester** node: It can generate 5 different prompts based on the original prompt using consistent in the options or random prompts using random in the options.
|
||||
Works best with **LLava 1.5** and **1.6**.
|
||||
- Works best with **LLava 1.5** and **1.6**.
|
||||
|
||||
**Play with the ```temperature``` for creative or consistent results. Higher the temperature more creative are the results.**
|
||||
If you want to dive deep into [LLM Settings](https://www.promptingguide.ai/introduction/settings)
|
||||
@@ -57,10 +55,21 @@ This LLM's works best for now for prompt generation.
|
||||
- DeepSeek
|
||||
You can use them for simple chat also there is an option in the node.
|
||||
|
||||
## UForm-Gen2 Qwen Node
|
||||
UForm-Gen2 is an extremely fast small generative vision-language model primarily designed for Image Captioning and Visual Question Answering.
|
||||
[UForm-Gen2 Qwen](https://huggingface.co/unum-cloud/uform-gen2-qwen-500m)
|
||||
It will automatically download the necessary files into ```custom_nodes/ComfyUI_VLM_nodes/nodes/files_for_uform_gen2_qwen```
|
||||
|
||||
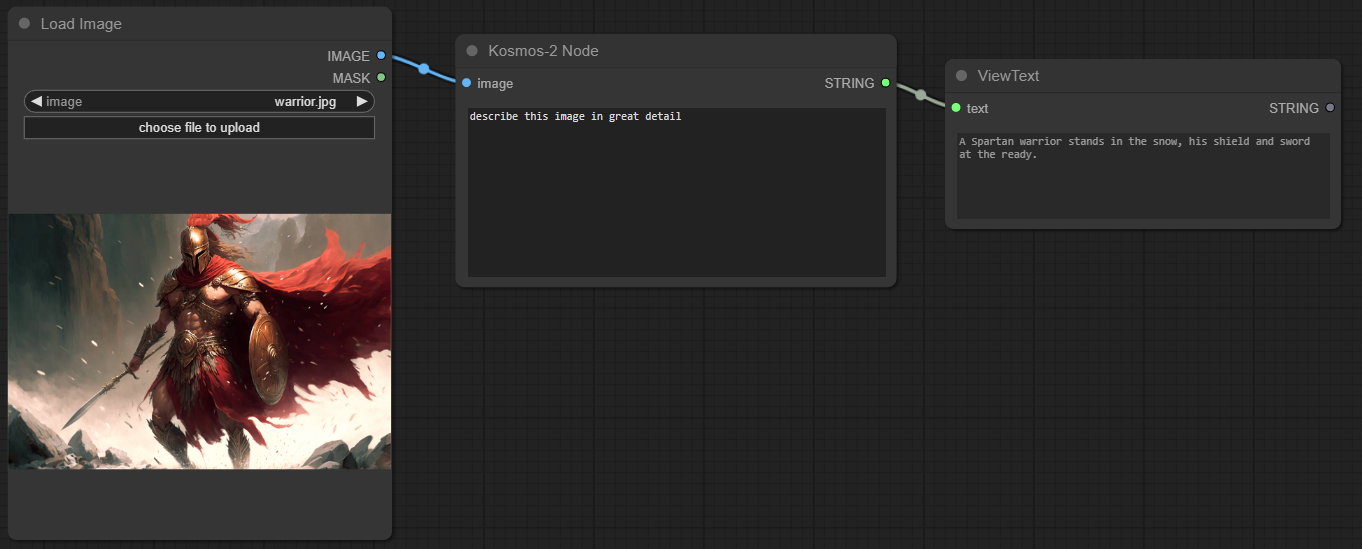
## Kosmos-2 Node
|
||||
Kosmos-2: Grounding Multimodal Large Language Models to the World.
|
||||
[Kosmos-2](https://huggingface.co/microsoft/kosmos-2-patch14-224)
|
||||
It will automatically download the necessary files into ```custom_nodes/ComfyUI_VLM_nodes/nodes/files_for_kosmos2```
|
||||
|
||||
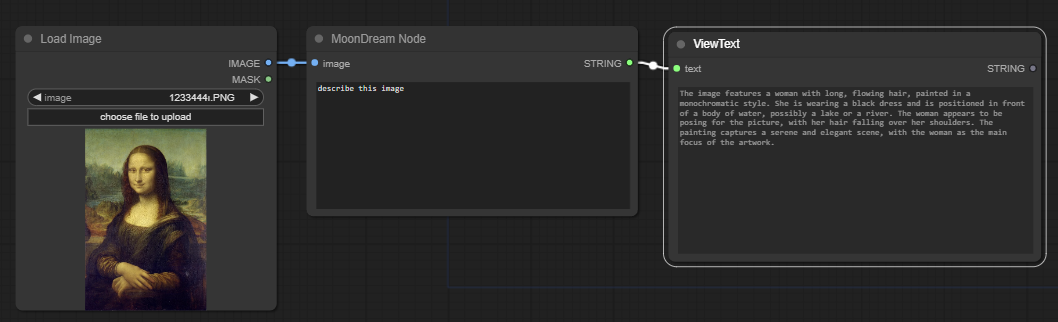
## moondream Node
|
||||
This node is designed to work with the Moondream model, a powerful small vision language model built by @vikhyatk using SigLIP, Phi-1.5, and the LLaVa training dataset.
|
||||
The model boasts 1.6 billion parameters and is made available for research purposes only; commercial use is not allowed.
|
||||
It will automatically download the necessary files into ```custom_nodes/ComfyUI_VLM_nodes/nodes/files_for__moondream```
|
||||
|
||||
## JoyTag Node
|
||||
@fpgamine's JoyTag is a state of the art AI vision model for tagging images, with a focus on sex positivity and inclusivity.
|
||||
It uses the Danbooru tagging schema, but works across a wide range of images, from hand drawn to photographic.
|
||||
@@ -68,15 +77,18 @@ It will automatically download the necessary files into ```custom_nodes/ComfyUI_
|
||||
## Example LLaVa Nodes
|
||||
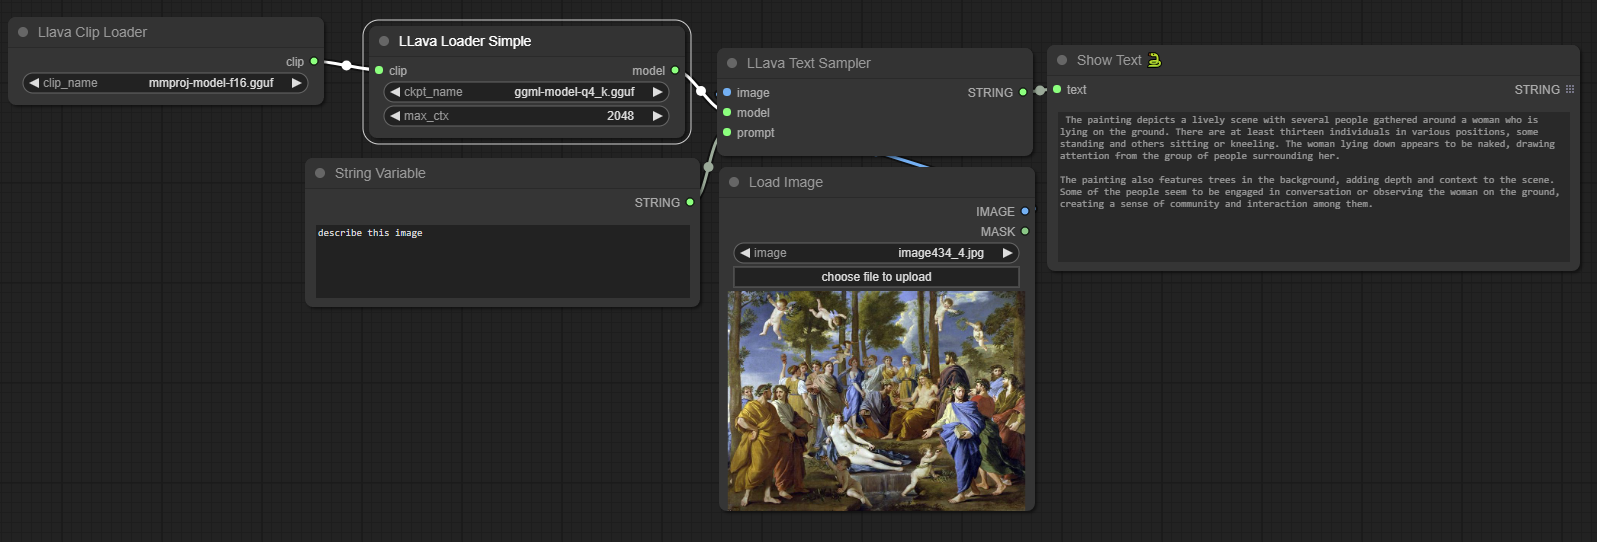
|
||||
|
||||
## Example InternLM-XComposer Node
|
||||
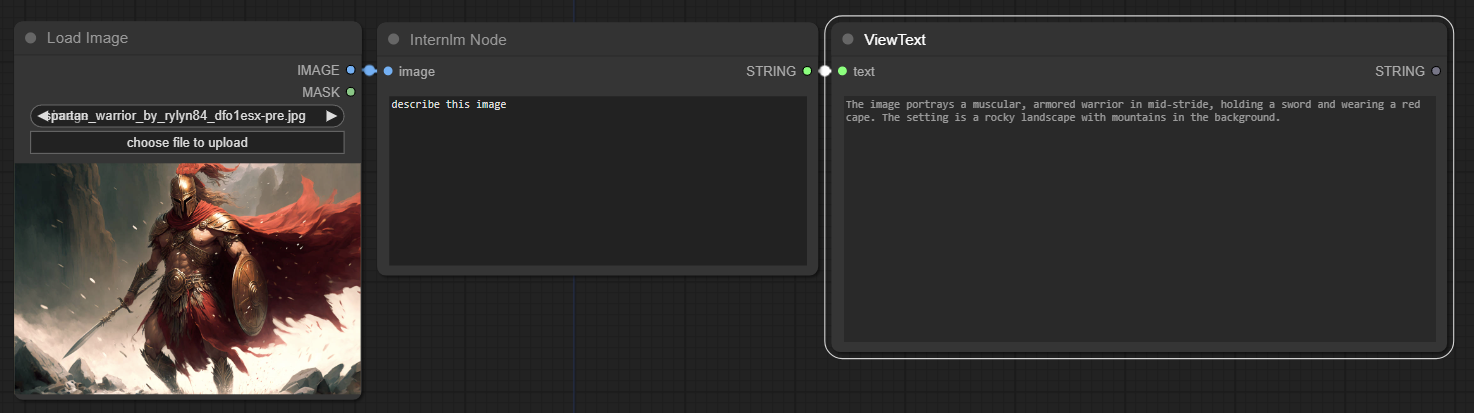
|
||||
|
||||
## Example Using Automatic Prompt Generation
|
||||
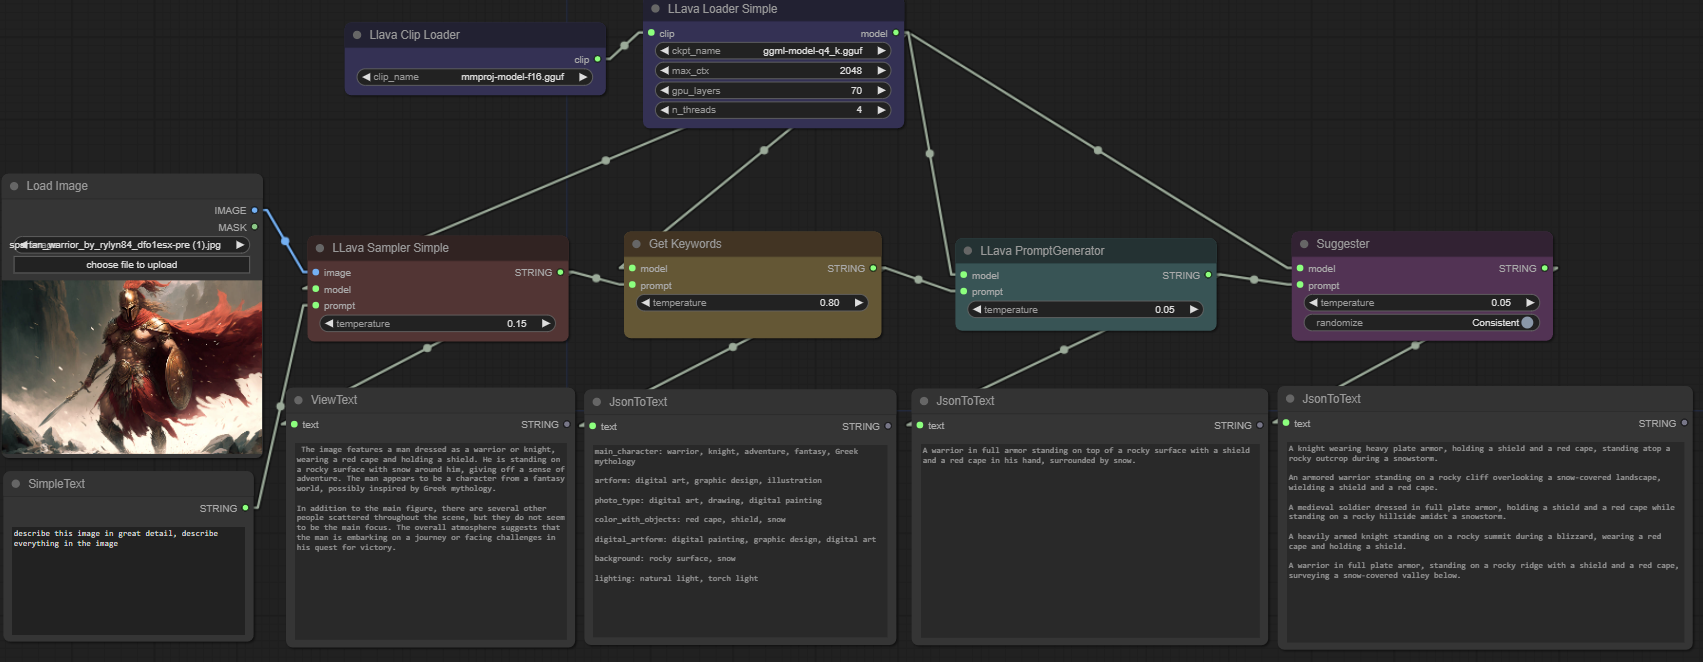
|
||||
|
||||
## LLM Nodes
|
||||

|
||||
|
||||
## Example UForm-Gen2 Qwen Node
|
||||
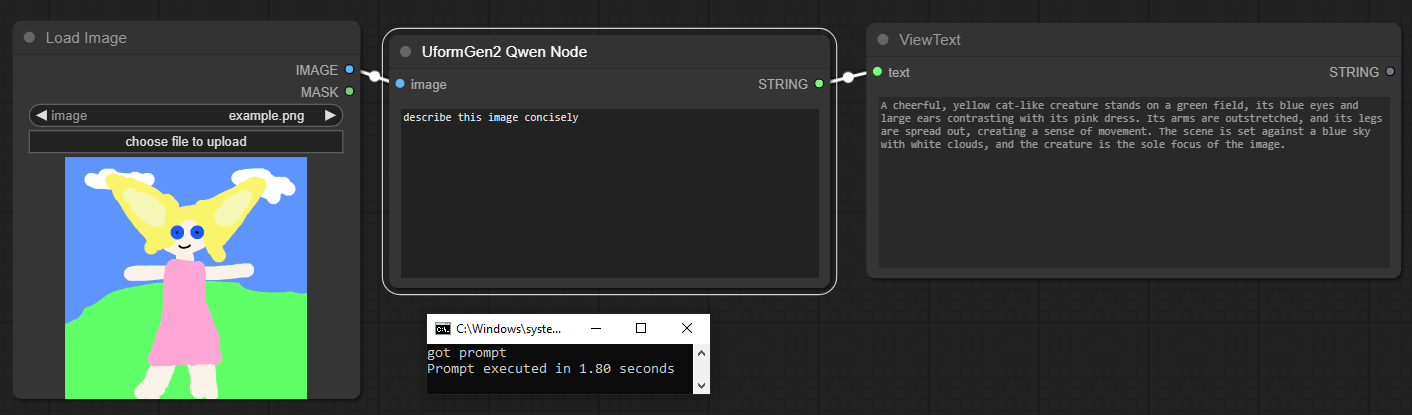
|
||||
|
||||
# Example Kosmos-2 Node
|
||||
|
||||
|
||||
## Example moondream
|
||||
|
||||
|
||||
|
||||
+20
-6
@@ -4,7 +4,18 @@ import importlib
|
||||
import pkg_resources
|
||||
import sys
|
||||
import subprocess
|
||||
import folder_paths
|
||||
|
||||
supported_LLava_extensions = set(['.gguf'])
|
||||
|
||||
try:
|
||||
folder_paths.folder_names_and_paths["LLavacheckpoints"] = (folder_paths.folder_names_and_paths["LLavacheckpoints"][0], supported_LLava_extensions)
|
||||
except:
|
||||
# check if LLavacheckpoints exists otherwise create
|
||||
if not os.path.isdir(os.path.join(folder_paths.models_dir, "LLavacheckpoints")):
|
||||
os.mkdir(os.path.join(folder_paths.models_dir, "LLavacheckpoints"))
|
||||
|
||||
folder_paths.folder_names_and_paths["LLavacheckpoints"] = ([os.path.join(folder_paths.models_dir, "LLavacheckpoints")], supported_LLava_extensions)
|
||||
# Define the check_requirements_installed function here or import it
|
||||
def check_requirements_installed(requirements_path):
|
||||
with open(requirements_path, 'r') as f:
|
||||
@@ -25,12 +36,10 @@ def check_requirements_installed(requirements_path):
|
||||
requirements_path = os.path.join(os.path.dirname(os.path.realpath(__file__)), "requirements.txt")
|
||||
check_requirements_installed(requirements_path)
|
||||
|
||||
from .install_init import init, get_system_info, install_llama, install_autogptq
|
||||
system_info = get_system_info()
|
||||
install_llama(system_info)
|
||||
from .install_init import init, install_llama
|
||||
install_llama()
|
||||
llama_cpp_agent_path = os.path.join(os.path.dirname(os.path.realpath(__file__)), "cpp_agent_req.txt")
|
||||
check_requirements_installed(llama_cpp_agent_path)
|
||||
install_autogptq(system_info)
|
||||
init()
|
||||
|
||||
node_list = [
|
||||
@@ -39,7 +48,11 @@ node_list = [
|
||||
"llavaloader",
|
||||
"suggest",
|
||||
"joytag",
|
||||
"internlm",
|
||||
"uform",
|
||||
"kosmos2",
|
||||
"audioldm2",
|
||||
"playmusic",
|
||||
"moondream2",
|
||||
]
|
||||
|
||||
NODE_CLASS_MAPPINGS = {}
|
||||
@@ -51,6 +64,7 @@ for module_name in node_list:
|
||||
NODE_CLASS_MAPPINGS = {**NODE_CLASS_MAPPINGS, **imported_module.NODE_CLASS_MAPPINGS}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {**NODE_DISPLAY_NAME_MAPPINGS, **imported_module.NODE_DISPLAY_NAME_MAPPINGS}
|
||||
|
||||
WEB_DIRECTORY = "./web"
|
||||
__all__ = ["NODE_CLASS_MAPPINGS", "NODE_DISPLAY_NAME_MAPPINGS", "WEB_DIRECTORY"]
|
||||
|
||||
__all__ = ["NODE_CLASS_MAPPINGS", "NODE_DISPLAY_NAME_MAPPINGS"]
|
||||
|
||||
|
||||
+2
-2
@@ -1,5 +1,5 @@
|
||||
llama-cpp-agent
|
||||
llama-cpp-agent==0.0.17
|
||||
mkdocs
|
||||
mkdocs-material
|
||||
mkdocstrings[python]
|
||||
docstring-parser
|
||||
docstring-parser
|
||||
|
||||
+114
-103
@@ -9,7 +9,6 @@ import sys
|
||||
import importlib.util
|
||||
import re
|
||||
import torch
|
||||
import cpuinfo
|
||||
import packaging.tags
|
||||
from requests import get
|
||||
import asyncio
|
||||
@@ -20,50 +19,6 @@ from tqdm import tqdm
|
||||
import pkg_resources
|
||||
|
||||
|
||||
|
||||
def get_python_version():
|
||||
"""Return the Python version in a concise format, e.g., '39' for Python 3.9."""
|
||||
version_match = re.match(r"3\.(\d+)", platform.python_version())
|
||||
if version_match:
|
||||
return "3" + version_match.group(1)
|
||||
else:
|
||||
return None
|
||||
|
||||
def get_system_info():
|
||||
"""Gather system information related to NVIDIA GPU, CUDA version, AVX2 support, Python version, OS, and platform tag."""
|
||||
system_info = {
|
||||
'gpu': False,
|
||||
'cuda_version': None,
|
||||
'avx2': False,
|
||||
'python_version': get_python_version(),
|
||||
'os': platform.system(),
|
||||
'os_bit': platform.architecture()[0].replace("bit", ""),
|
||||
'platform_tag': None,
|
||||
}
|
||||
|
||||
# Check for NVIDIA GPU and CUDA version
|
||||
if importlib.util.find_spec('torch'):
|
||||
system_info['gpu'] = torch.cuda.is_available()
|
||||
if system_info['gpu']:
|
||||
system_info['cuda_version'] = "cu" + torch.version.cuda.replace(".", "").strip()
|
||||
|
||||
# Check for AVX2 support
|
||||
if importlib.util.find_spec('cpuinfo'):
|
||||
system_info['avx2'] = 'avx2' in cpuinfo.get_cpu_info()['flags']
|
||||
|
||||
# Determine the platform tag
|
||||
if importlib.util.find_spec('packaging.tags'):
|
||||
system_info['platform_tag'] = next(packaging.tags.sys_tags()).platform
|
||||
|
||||
return system_info
|
||||
|
||||
def latest_lamacpp():
|
||||
try:
|
||||
response = get("https://api.github.com/repos/abetlen/llama-cpp-python/releases/latest")
|
||||
return response.json()["tag_name"].replace("v", "")
|
||||
except Exception:
|
||||
return "0.2.20"
|
||||
|
||||
def install_package(package_name, custom_command=None):
|
||||
if not package_is_installed(package_name):
|
||||
print(f"Installing {package_name}...")
|
||||
@@ -77,55 +32,14 @@ def install_package(package_name, custom_command=None):
|
||||
def package_is_installed(package_name):
|
||||
return importlib.util.find_spec(package_name) is not None
|
||||
|
||||
def install_llama(system_info):
|
||||
def install_llama():
|
||||
"""Install llama-cpp-python with consideration for macOS or other OS specifics."""
|
||||
imported = package_is_installed("llama-cpp-python") or package_is_installed("llama_cpp")
|
||||
if imported:
|
||||
print("llama-cpp installed")
|
||||
if not imported:
|
||||
install_package("llama-cpp-python")
|
||||
|
||||
else:
|
||||
lcpp_version = latest_lamacpp()
|
||||
base_url = "https://github.com/abetlen/llama-cpp-python/releases/download/v"
|
||||
avx = "AVX2" if system_info['avx2'] else "AVX"
|
||||
if system_info['gpu']:
|
||||
cuda_version = system_info['cuda_version']
|
||||
custom_command = f"--force-reinstall --no-deps --index-url=https://jllllll.github.io/llama-cpp-python-cuBLAS-wheels/{avx}/{cuda_version}"
|
||||
else:
|
||||
custom_command = f"{base_url}{lcpp_version}/llama_cpp_python-{lcpp_version}-{system_info['platform_tag']}.whl"
|
||||
install_package("llama-cpp-python", custom_command=custom_command)
|
||||
|
||||
def install_autogptq(system_info):
|
||||
# Check OS compatibility
|
||||
imported = package_is_installed("auto_gptq")
|
||||
if imported:
|
||||
print("AutoGPTQ installed")
|
||||
else:
|
||||
if system_info['os'] not in ['Linux', 'Windows']:
|
||||
print("AutoGPTQ is not supported on your operating system.")
|
||||
return
|
||||
|
||||
# Prepare base install command
|
||||
base_command = [sys.executable, "-m", "pip", "install", "auto-gptq"]
|
||||
|
||||
# Determine the specific install command based on GPU and CUDA/ROCm version
|
||||
if system_info['gpu']:
|
||||
if 'cuda_version' in system_info and system_info['cuda_version'] in ['cu118', 'cu121']:
|
||||
if system_info['cuda_version'] == 'cu118':
|
||||
base_command += ["--extra-index-url", "https://huggingface.github.io/autogptq-index/whl/cu118/"]
|
||||
# No extra URL needed for cu121 as it's the default
|
||||
elif 'rocm_version' in system_info and system_info['rocm_version'] == 'rocm573':
|
||||
base_command += ["--extra-index-url", "https://huggingface.github.io/autogptq-index/whl/rocm573/"]
|
||||
else:
|
||||
print("Unsupported GPU configuration for AutoGPTQ.")
|
||||
return
|
||||
else:
|
||||
print("No GPU detected. AutoGPTQ installation requires a GPU with CUDA or ROCm support.")
|
||||
return
|
||||
|
||||
# Execute the installation command
|
||||
try:
|
||||
print(f"Installing AutoGPTQ with command: {' '.join(base_command)}")
|
||||
subprocess.check_call(base_command)
|
||||
except Exception as e:
|
||||
print(f"Failed to install AutoGPTQ: {e}")
|
||||
print("llama-cpp-python is already installed.")
|
||||
|
||||
config = None
|
||||
|
||||
@@ -178,17 +92,28 @@ def get_web_ext_dir():
|
||||
dir = os.path.join(dir, name)
|
||||
return dir
|
||||
|
||||
|
||||
def get_extension_config(reload=False):
|
||||
global config
|
||||
if reload == False and config is not None:
|
||||
return config
|
||||
|
||||
config_path = get_ext_dir("vlmnodes.json")
|
||||
default_config_path = get_ext_dir("vlmnodes.default.json")
|
||||
if not os.path.exists(config_path):
|
||||
log("Missing vlmnodes.json, this extension may not work correctly. Please reinstall the extension.",
|
||||
type="ERROR", always=True, name="???")
|
||||
print(f"Extension path: {get_ext_dir()}")
|
||||
return {"name": "Unknown", "version": -1}
|
||||
if os.path.exists(default_config_path):
|
||||
shutil.copy(default_config_path, config_path)
|
||||
if not os.path.exists(config_path):
|
||||
log(f"Failed to create config at {config_path}", type="ERROR", always=True, name="???")
|
||||
print(f"Extension path: {get_ext_dir()}")
|
||||
return {"name": "Unknown", "version": -1}
|
||||
|
||||
else:
|
||||
log("Missing pysssss.default.json, this extension may not work correctly. Please reinstall the extension.",
|
||||
type="ERROR", always=True, name="???")
|
||||
print(f"Extension path: {get_ext_dir()}")
|
||||
return {"name": "Unknown", "version": -1}
|
||||
|
||||
with open(config_path, "r") as f:
|
||||
config = json.loads(f.read())
|
||||
return config
|
||||
@@ -220,24 +145,43 @@ def is_junction(path):
|
||||
return False
|
||||
|
||||
def install_js():
|
||||
src_dir = get_ext_dir("js")
|
||||
src_dir = get_ext_dir("web/js")
|
||||
if not os.path.exists(src_dir):
|
||||
log("No JS")
|
||||
return
|
||||
|
||||
should_install = should_install_js()
|
||||
if should_install:
|
||||
log("it looks like you're running an old version of ComfyUI that requires manual setup of web files, it is recommended you update your installation.", "warning", True)
|
||||
dst_dir = get_web_ext_dir()
|
||||
|
||||
if os.path.exists(dst_dir):
|
||||
if os.path.islink(dst_dir) or is_junction(dst_dir):
|
||||
log("JS already linked")
|
||||
return
|
||||
elif link_js(src_dir, dst_dir):
|
||||
linked = os.path.islink(dst_dir) or is_junction(dst_dir)
|
||||
if linked or os.path.exists(dst_dir):
|
||||
if linked:
|
||||
if should_install:
|
||||
log("JS already linked")
|
||||
else:
|
||||
os.unlink(dst_dir)
|
||||
log("JS unlinked, PromptServer will serve extension")
|
||||
elif not should_install:
|
||||
shutil.rmtree(dst_dir)
|
||||
log("JS deleted, PromptServer will serve extension")
|
||||
return
|
||||
|
||||
if not should_install:
|
||||
log("JS skipped, PromptServer will serve extension")
|
||||
return
|
||||
|
||||
if link_js(src_dir, dst_dir):
|
||||
log("JS linked")
|
||||
return
|
||||
|
||||
log("Copying JS files")
|
||||
shutil.copytree(src_dir, dst_dir, dirs_exist_ok=True)
|
||||
|
||||
def should_install_js():
|
||||
return not hasattr(PromptServer.instance, "supports") or "custom_nodes_from_web" not in PromptServer.instance.supports
|
||||
|
||||
|
||||
def init(check_imports=None):
|
||||
log("Init")
|
||||
|
||||
@@ -253,6 +197,7 @@ def init(check_imports=None):
|
||||
install_js()
|
||||
return True
|
||||
|
||||
|
||||
def get_async_loop():
|
||||
loop = None
|
||||
try:
|
||||
@@ -262,10 +207,12 @@ def get_async_loop():
|
||||
asyncio.set_event_loop(loop)
|
||||
return loop
|
||||
|
||||
|
||||
def get_http_session():
|
||||
loop = get_async_loop()
|
||||
return aiohttp.ClientSession(loop=loop)
|
||||
|
||||
|
||||
async def download(url, stream, update_callback=None, session=None):
|
||||
close_session = False
|
||||
if session is None:
|
||||
@@ -292,18 +239,82 @@ async def download(url, stream, update_callback=None, session=None):
|
||||
if close_session and session is not None:
|
||||
await session.close()
|
||||
|
||||
|
||||
async def download_to_file(url, destination, update_callback=None, is_ext_subpath=True, session=None):
|
||||
if is_ext_subpath:
|
||||
destination = get_ext_dir(destination)
|
||||
with open(destination, mode='wb') as f:
|
||||
download(url, f, update_callback, session)
|
||||
|
||||
|
||||
def wait_for_async(async_fn, loop=None):
|
||||
res = []
|
||||
|
||||
async def run_async():
|
||||
r = await async_fn()
|
||||
res.append(r)
|
||||
|
||||
if loop is None:
|
||||
try:
|
||||
loop = asyncio.get_event_loop()
|
||||
except:
|
||||
loop = asyncio.new_event_loop()
|
||||
asyncio.set_event_loop(loop)
|
||||
|
||||
loop.run_until_complete(run_async())
|
||||
|
||||
return res[0]
|
||||
|
||||
|
||||
def update_node_status(client_id, node, text, progress=None):
|
||||
if client_id is None:
|
||||
client_id = PromptServer.instance.client_id
|
||||
|
||||
if client_id is None:
|
||||
return
|
||||
|
||||
PromptServer.instance.send_sync("vlmnodes/update_status", {
|
||||
"node": node,
|
||||
"progress": progress,
|
||||
"text": text
|
||||
}, client_id)
|
||||
|
||||
|
||||
async def update_node_status_async(client_id, node, text, progress=None):
|
||||
if client_id is None:
|
||||
client_id = PromptServer.instance.client_id
|
||||
|
||||
if client_id is None:
|
||||
return
|
||||
|
||||
await PromptServer.instance.send("vlmnodes/update_status", {
|
||||
"node": node,
|
||||
"progress": progress,
|
||||
"text": text
|
||||
}, client_id)
|
||||
|
||||
|
||||
def get_config_value(key, default=None, throw=False):
|
||||
split = key.split(".")
|
||||
obj = get_extension_config()
|
||||
for s in split:
|
||||
if s in obj:
|
||||
obj = obj[s]
|
||||
else:
|
||||
if throw:
|
||||
raise KeyError("Configuration key missing: " + key)
|
||||
else:
|
||||
return default
|
||||
return obj
|
||||
|
||||
|
||||
def is_inside_dir(root_dir, check_path):
|
||||
root_dir = os.path.abspath(root_dir)
|
||||
if not os.path.isabs(check_path):
|
||||
check_path = os.path.abspath(os.path.join(root_dir, check_path))
|
||||
return os.path.commonpath([check_path, root_dir]) == root_dir
|
||||
|
||||
|
||||
def get_child_dir(root_dir, child_path, throw_if_outside=True):
|
||||
child_path = os.path.abspath(os.path.join(root_dir, child_path))
|
||||
if is_inside_dir(root_dir, child_path):
|
||||
|
||||
@@ -0,0 +1,131 @@
|
||||
from huggingface_hub import snapshot_download
|
||||
from pathlib import Path
|
||||
import torch
|
||||
import os
|
||||
import soundfile as sf
|
||||
from folder_paths import output_directory
|
||||
import folder_paths
|
||||
import datetime
|
||||
from pathlib import Path
|
||||
|
||||
# Define the directory for saving files related to the audio model
|
||||
files_for_audio_model = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for_audioldm2"
|
||||
files_for_audio_model.mkdir(parents=True, exist_ok=True) # Ensure the directory exists
|
||||
|
||||
class AnyType(str):
|
||||
def __ne__(self, __value: object) -> bool:
|
||||
return False
|
||||
base_path = os.path.dirname(os.path.realpath(__file__))
|
||||
|
||||
# Our any instance wants to be a wildcard string
|
||||
any = AnyType("*")
|
||||
class AudioLDM2ModelPredictor:
|
||||
|
||||
def __init__(self):
|
||||
from diffusers import AudioLDM2Pipeline
|
||||
self.device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
torch_dtype = torch.float16 if self.device == "cuda" else torch.float32
|
||||
|
||||
# Use snapshot_download to manage the model download/cache
|
||||
self.model_path = snapshot_download("cvssp/audioldm2",
|
||||
local_dir=files_for_audio_model,
|
||||
force_download=False, # Set to True to always download
|
||||
local_files_only=False, # Download if not available locally
|
||||
use_auth_token=False, # Set to True if using a private model
|
||||
local_dir_use_symlinks="auto", # Auto-manage symlinks
|
||||
ignore_patterns=["*.bin", "*.jpg", "*.png"]) # Ignore unrelated files
|
||||
|
||||
self.pipeline = AudioLDM2Pipeline.from_pretrained(self.model_path,
|
||||
torch_dtype=torch_dtype).to(self.device)
|
||||
self.generator = torch.Generator(self.device)
|
||||
|
||||
def generate_audio(self, text, negative_prompt, duration, guidance_scale, random_seed, sample_rate, n_candidates=1, extension="wav"):
|
||||
if text is None:
|
||||
raise ValueError("Please provide a text input.")
|
||||
|
||||
# Manual seed for reproducibility
|
||||
self.generator.manual_seed(int(random_seed))
|
||||
|
||||
# Generate audio
|
||||
waveforms = self.pipeline(
|
||||
text,
|
||||
audio_length_in_s=duration,
|
||||
guidance_scale=guidance_scale,
|
||||
num_inference_steps=200,
|
||||
negative_prompt=negative_prompt,
|
||||
num_waveforms_per_prompt=n_candidates,
|
||||
generator=self.generator,
|
||||
)["audios"]
|
||||
|
||||
final_waveforms = waveforms[0].tolist()
|
||||
return (final_waveforms, sample_rate) # Return the path of the generated audio file
|
||||
|
||||
|
||||
class AudioLDM2Node:
|
||||
def __init__(self):
|
||||
self.predictor = AudioLDM2ModelPredictor()
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"text": ("STRING",{"default": "", "forceInput": True}),
|
||||
"negative_prompt": ("STRING",{"default": "", "forceInput": True}),
|
||||
"duration": ("INT",{"default": 10, "min": 1, "max": 60, "step": 1}),
|
||||
"guidance_scale": ("FLOAT", {"default": 3.5, "min": 0.1, "max": 20.0, "step": 0.1}),
|
||||
"seed": ("INT", {"default": 42, "step": 1}),
|
||||
"n_candidates": ("INT", {"default": 3, "min": 1, "max": 10, "step": 1}),
|
||||
"sample_rate": ("INT", {"default": 16000, "min": 8000, "max": 48000, "step": 1}),
|
||||
"extension": (["wav", "mp3", "flac"], {"default": "wav"}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_NAMES = ("wave_form", "sample_rate", )
|
||||
RETURN_TYPES = (any, "INT", )
|
||||
OUTPUT_NODE = True
|
||||
FUNCTION = "generate_audio_final"
|
||||
|
||||
CATEGORY = "VLM Nodes/Audio"
|
||||
|
||||
def generate_audio_final(self, text, negative_prompt, duration, guidance_scale, sample_rate, seed, n_candidates, extension):
|
||||
wave_form, sample_rate_final = self.predictor.generate_audio(text, negative_prompt, duration, guidance_scale, seed, sample_rate, n_candidates, extension)
|
||||
return (wave_form, sample_rate_final, )
|
||||
|
||||
class SaveAudioNode:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"waveforms": (any, {}), # Assuming 'any' is a placeholder for the actual data type
|
||||
"sample_rate": ("INT", {"forceInput": True}),
|
||||
"extension": (["wav", "mp3", "flac"], {"default": "wav"}) # mp3, wav, flac
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ()
|
||||
FUNCTION = "save_audio"
|
||||
CATEGORY = "VLM Nodes/Audio"
|
||||
OUTPUT_NODE = True
|
||||
|
||||
def save_audio(self, waveforms, sample_rate, extension):
|
||||
# Define the date format
|
||||
date_formats = {
|
||||
'yyyyMMdd_HHmmss': lambda d: '{}{:02d}{:02d}_{:02d}{:02d}{:02d}'.format(d.year, d.month, d.day, d.hour, d.minute, d.second),
|
||||
}
|
||||
|
||||
# Generate the date-based prefix
|
||||
current_datetime = datetime.datetime.now()
|
||||
print(current_datetime.hour, current_datetime.minute, current_datetime.second)
|
||||
for format_key, format_lambda in date_formats.items():
|
||||
preset_prefix = f"{format_lambda(current_datetime)}"
|
||||
|
||||
# Build the filename and save the audio
|
||||
audio_path = Path(output_directory) / f"{preset_prefix}_audio.{extension}"
|
||||
sf.write(audio_path.as_posix(), waveforms, sample_rate)
|
||||
|
||||
return ()
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"AudioLDM2Node": AudioLDM2Node,
|
||||
"SaveAudioNode": SaveAudioNode}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"AudioLDM2Node": "AudioLDM-2 Node",
|
||||
"SaveAudioNode": "Save Audio Node"}
|
||||
@@ -1,90 +0,0 @@
|
||||
from .joytagger import Models
|
||||
from PIL import Image
|
||||
import torch.amp.autocast_mode
|
||||
from pathlib import Path
|
||||
import torch
|
||||
import torchvision.transforms.functional as TVF
|
||||
from huggingface_hub import snapshot_download
|
||||
from torchvision import transforms
|
||||
import torch, auto_gptq
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
from auto_gptq.modeling._base import BaseGPTQForCausalLM
|
||||
from io import BytesIO
|
||||
from torchvision.transforms import ToPILImage
|
||||
|
||||
# Define your local directory where you want to save the files
|
||||
files_for_internlm = Path(__file__).resolve().parent / "files_for_internlm"
|
||||
|
||||
# Check if the directory exists, create if it doesn't (optional)
|
||||
files_for_internlm.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
class InternLMXComposer2QForCausalLM(BaseGPTQForCausalLM):
|
||||
layers_block_name = "model.layers"
|
||||
outside_layer_modules = [
|
||||
'vit', 'vision_proj', 'model.tok_embeddings', 'model.norm', 'output',
|
||||
]
|
||||
inside_layer_modules = [
|
||||
["attention.wqkv.linear"],
|
||||
["attention.wo.linear"],
|
||||
["feed_forward.w1.linear", "feed_forward.w3.linear"],
|
||||
["feed_forward.w2.linear"],
|
||||
]
|
||||
def download_internlm():
|
||||
# Ensure the correct behavior based on the existence of the local directory
|
||||
print(f"Target directory for download: {files_for_internlm}")
|
||||
|
||||
# Call snapshot_download with specified parameters
|
||||
path = snapshot_download(
|
||||
"internlm/internlm-xcomposer2-vl-7b-4bit", # Example repo_id
|
||||
local_dir=files_for_internlm,
|
||||
force_download=False, # Set to True if you always want to download, regardless of local copy
|
||||
local_files_only=False, # Set to False to allow downloading if not available locally
|
||||
local_dir_use_symlinks="auto" # or set to True/False based on your symlink preference
|
||||
)
|
||||
print(f"Model path: {path}")
|
||||
return path
|
||||
|
||||
class Internlm:
|
||||
def __init__(self):
|
||||
pass
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"question": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "",
|
||||
},
|
||||
),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
|
||||
FUNCTION = "internlm_chat"
|
||||
|
||||
CATEGORY = "VLM Nodes/Internlm"
|
||||
|
||||
def internlm_chat(self, image, question):
|
||||
model_path = download_internlm()
|
||||
print(f"Model path: {model_path}")
|
||||
model = InternLMXComposer2QForCausalLM.from_quantized(model_path , trust_remote_code=True, device="cuda:0").eval()
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_path , trust_remote_code=True)
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
temp_path = files_for_internlm / "temp.jpg"
|
||||
pil_image.save(temp_path)
|
||||
text = f'<ImageHere>{question}'
|
||||
with torch.cuda.amp.autocast():
|
||||
response, _ = model.chat(tokenizer, query=text, image=str(temp_path), history=[], do_sample=False)
|
||||
return (response, )
|
||||
|
||||
# A dictionary that contains all nodes you want to export with their names
|
||||
NODE_CLASS_MAPPINGS = {"Internlm": Internlm}
|
||||
|
||||
# A dictionary that contains the friendly/humanly readable titles for the nodes
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Internlm": "Internlm Node"}
|
||||
+10
-4
@@ -7,11 +7,17 @@ import torchvision.transforms.functional as TVF
|
||||
from huggingface_hub import snapshot_download
|
||||
from torchvision import transforms
|
||||
import os
|
||||
import folder_paths
|
||||
|
||||
if torch.cuda.is_available():
|
||||
DEVICE = "cuda"
|
||||
else:
|
||||
DEVICE = "cpu"
|
||||
|
||||
THRESHOLD = 0.4
|
||||
|
||||
# Define your local directory where you want to save the files
|
||||
files_for_joytagger = Path(__file__).resolve().parent / "files_for_joytagger"
|
||||
files_for_joytagger = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for_joytagger"
|
||||
|
||||
# Check if the directory exists, create if it doesn't (optional)
|
||||
files_for_joytagger.mkdir(parents=True, exist_ok=True)
|
||||
@@ -95,7 +101,7 @@ class Joytag:
|
||||
def tags(self, image, tag_number):
|
||||
path = download_joytag()
|
||||
print(f"Model path: {path}")
|
||||
model = Models.VisionModel.load_model(Path(path), device='cuda')
|
||||
model = Models.VisionModel.load_model(Path(path), device=DEVICE)
|
||||
model.eval()
|
||||
with open(Path(path) / 'top_tags.txt', 'r') as f:
|
||||
top_tags = [line.strip() for line in f.readlines() if line.strip()]
|
||||
@@ -104,10 +110,10 @@ class Joytag:
|
||||
def predict(image: Image.Image):
|
||||
image_tensor = prepare_image(image, model.image_size)
|
||||
batch = {
|
||||
'image': image_tensor.unsqueeze(0).to('cuda'),
|
||||
'image': image_tensor.unsqueeze(0).to(DEVICE),
|
||||
}
|
||||
|
||||
with torch.amp.autocast_mode.autocast('cuda', enabled=True):
|
||||
with torch.amp.autocast_mode.autocast(DEVICE, enabled=True):
|
||||
preds = model(batch)
|
||||
tag_preds = preds['tags'].sigmoid().cpu()
|
||||
|
||||
|
||||
@@ -210,11 +210,12 @@ class FastCLIPAttention2(nn.Module):
|
||||
k_states = k_states.view(bsz, src_len, self.num_heads, self.head_dim).transpose(1, 2) # (bsz, num_heads, src_len, head_dim)
|
||||
v_states = v_states.view(bsz, src_len, self.num_heads, self.head_dim).transpose(1, 2) # (bsz, num_heads, src_len, head_dim)
|
||||
|
||||
# Performs scale of query_states, attention, and softmax
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False):
|
||||
x = F.scaled_dot_product_attention(q_states, k_states, v_states) # (bsz, num_heads, tgt_len, head_dim)
|
||||
x = x.transpose(1, 2).contiguous().view(bsz, tgt_len, embed_dim) # (bsz, tgt_len, embed_dim)
|
||||
|
||||
if torch.cuda.is_available():
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False):
|
||||
pass
|
||||
x = F.scaled_dot_product_attention(q_states, k_states, v_states) # (bsz, num_heads, tgt_len, head_dim)
|
||||
x = x.transpose(1, 2).contiguous().view(bsz, tgt_len, embed_dim) # (bsz, tgt_len, embed_dim)
|
||||
|
||||
# Projection
|
||||
x = self.out_proj(x) # (bsz, tgt_len, out_dim)
|
||||
|
||||
@@ -865,9 +866,12 @@ class ViTBlock(nn.Module):
|
||||
k_states = qkv_states[1].view(bsz, src_len, self.num_heads, embed_dim // self.num_heads).transpose(1, 2) # (bsz, num_heads, src_len, embed_dim // num_heads)
|
||||
v_states = qkv_states[2].view(bsz, src_len, self.num_heads, embed_dim // self.num_heads).transpose(1, 2) # (bsz, num_heads, src_len, embed_dim // num_heads)
|
||||
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False):
|
||||
out = F.scaled_dot_product_attention(q_states, k_states, v_states) # (bsz, num_heads, tgt_len, head_dim)
|
||||
out = out.transpose(1, 2).contiguous().view(bsz, src_len, embed_dim) # (bsz, tgt_len, embed_dim)
|
||||
if torch.cuda.is_available():
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False):
|
||||
pass
|
||||
|
||||
out = F.scaled_dot_product_attention(q_states, k_states, v_states) # (bsz, num_heads, tgt_len, head_dim)
|
||||
out = out.transpose(1, 2).contiguous().view(bsz, src_len, embed_dim) # (bsz, tgt_len, embed_dim)
|
||||
|
||||
out = self.out_proj(out)
|
||||
|
||||
|
||||
@@ -0,0 +1,87 @@
|
||||
from transformers import AutoModelForVision2Seq, AutoProcessor
|
||||
from PIL import Image
|
||||
from pathlib import Path
|
||||
import torch
|
||||
from torchvision.transforms import ToPILImage
|
||||
from huggingface_hub import snapshot_download
|
||||
import folder_paths
|
||||
# Define the directory for saving files related to your new model
|
||||
files_for_new_model = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for_kosmos2"
|
||||
files_for_new_model.mkdir(parents=True, exist_ok=True) # Ensure the directory exists
|
||||
|
||||
class KosmosModelPredictor:
|
||||
def __init__(self):
|
||||
self.model_path = snapshot_download("microsoft/kosmos-2-patch14-224",
|
||||
local_dir=files_for_new_model,
|
||||
force_download=False, # Set to True if you always want to download, regardless of local copy
|
||||
local_files_only=False, # Set to False to allow downloading if not available locally
|
||||
local_dir_use_symlinks="auto",
|
||||
ignore_patterns=["*.bin", "*.jpg", "*.png"]) # or set to True/False based on your symlink preference
|
||||
self.device = "cuda:0" if torch.cuda.is_available() else "cpu"
|
||||
self.model = AutoModelForVision2Seq.from_pretrained(self.model_path).to(self.device)
|
||||
self.processor = AutoProcessor.from_pretrained(self.model_path)
|
||||
|
||||
def generate_predictions(self, image_path, main_text):
|
||||
# Load the image
|
||||
image_input = Image.open(image_path).convert("RGB")
|
||||
|
||||
text_input = f"<grounding>{main_text}: "
|
||||
|
||||
# Process the inputs
|
||||
inputs = self.processor(text=text_input, images=image_input, return_tensors="pt").to(self.device)
|
||||
|
||||
# Generate predictions
|
||||
generated_ids = self.model.generate(
|
||||
pixel_values=inputs["pixel_values"],
|
||||
input_ids=inputs["input_ids"],
|
||||
attention_mask=inputs["attention_mask"],
|
||||
image_embeds=None,
|
||||
image_embeds_position_mask=inputs["image_embeds_position_mask"],
|
||||
use_cache=True,
|
||||
max_new_tokens=128,
|
||||
)
|
||||
|
||||
# Decode the generated IDs
|
||||
generated_text = self.processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
|
||||
|
||||
# By default, the generated text is cleanup and the entities are extracted.
|
||||
processed_text, entities = self.processor.post_process_generation(generated_text)
|
||||
|
||||
return processed_text[len(main_text)+2:]
|
||||
|
||||
# Example of integrating NewModelPredictor into a node-like structure
|
||||
class Kosmos2model:
|
||||
def __init__(self):
|
||||
self.predictor = KosmosModelPredictor()
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"text_input": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "",
|
||||
},
|
||||
),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
|
||||
FUNCTION = "new_model_generate_predictions"
|
||||
|
||||
CATEGORY = "VLM Nodes/Kosmos-2"
|
||||
|
||||
def new_model_generate_predictions(self, image, text_input):
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
temp_path = files_for_new_model / "temp_image.png"
|
||||
pil_image.save(temp_path)
|
||||
|
||||
response = self.predictor.generate_predictions(temp_path, text_input)
|
||||
return (response, )
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"Kosmos2model": Kosmos2model}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Kosmos2model": "Kosmos-2 Node"}
|
||||
@@ -459,6 +459,7 @@ class CrossAttention(nn.Module):
|
||||
dtype=scores.dtype,
|
||||
device=scores.device,
|
||||
)
|
||||
key_padding_mask = key_padding_mask[:, :seqlen_k]
|
||||
padding_mask.masked_fill_(key_padding_mask, 0.0)
|
||||
|
||||
scores = scores + rearrange(padding_mask, "b s -> b 1 1 s")
|
||||
|
||||
@@ -0,0 +1,72 @@
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
from PIL import Image
|
||||
from pathlib import Path
|
||||
import torch
|
||||
from torchvision.transforms import ToPILImage
|
||||
from huggingface_hub import snapshot_download
|
||||
import folder_paths
|
||||
|
||||
|
||||
# Define the directory for saving files related to your new model
|
||||
files_for_moondream2 = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for_moondream2"
|
||||
files_for_moondream2.mkdir(parents=True, exist_ok=True) # Ensure the directory exists
|
||||
|
||||
class Moondream2Predictor:
|
||||
def __init__(self):
|
||||
self.model_path = snapshot_download("vikhyatk/moondream2",
|
||||
local_dir=files_for_moondream2,
|
||||
force_download=False, # Set to True if you always want to download, regardless of local copy
|
||||
local_files_only=False, # Set to False to allow downloading if not available locally
|
||||
revision="2024-03-04", # Specify the revision date for version control
|
||||
local_dir_use_symlinks="auto", # or set to True/False based on your symlink preference
|
||||
ignore_patterns=["*.bin", "*.jpg", "*.png", "*.gguf"]) # Customize based on need
|
||||
self.device = "cuda:0" if torch.cuda.is_available() else "cpu"
|
||||
self.model = AutoModelForCausalLM.from_pretrained(self.model_path, trust_remote_code=True).to(self.device)
|
||||
self.tokenizer = AutoTokenizer.from_pretrained(self.model_path)
|
||||
|
||||
def generate_predictions(self, image_path, question):
|
||||
# Load and process the image
|
||||
image_input = Image.open(image_path).convert("RGB")
|
||||
enc_image = self.model.encode_image(image_input)
|
||||
|
||||
# Generate predictions
|
||||
generated_text = self.model.answer_question(enc_image, question, self.tokenizer)
|
||||
|
||||
return generated_text
|
||||
|
||||
class Moondream2model:
|
||||
def __init__(self):
|
||||
self.predictor = Moondream2Predictor()
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"text_input": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "",
|
||||
},
|
||||
),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
|
||||
FUNCTION = "moondream2_generate_predictions"
|
||||
|
||||
CATEGORY = "VLM Nodes/Moondream2"
|
||||
|
||||
def moondream2_generate_predictions(self, image, text_input):
|
||||
# Convert tensor image to PIL Image
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
temp_path = files_for_moondream2 / "temp_image.png"
|
||||
pil_image.save(temp_path)
|
||||
|
||||
response = self.predictor.generate_predictions(temp_path, text_input)
|
||||
return (response, )
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"Moondream2model": Moondream2model}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Moondream2model": "Moondream-2 Node"}
|
||||
@@ -5,6 +5,7 @@ import os
|
||||
import hashlib
|
||||
from torchvision import transforms
|
||||
from pathlib import Path
|
||||
import folder_paths
|
||||
|
||||
if torch.cuda.is_available():
|
||||
DEVICE = "cuda"
|
||||
@@ -14,12 +15,11 @@ else:
|
||||
DTYPE = torch.float32
|
||||
|
||||
|
||||
output_directory = os.path.join(os.path.dirname(os.path.realpath(__file__)), "output")
|
||||
# Define your local directory where you want to save the files
|
||||
files_for_moondream = Path(__file__).resolve().parent / "files_for__moondream"
|
||||
|
||||
# Check if the directory exists, create if it doesn't (optional)
|
||||
files_for_moondream = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for__moondream"
|
||||
files_for_moondream.mkdir(parents=True, exist_ok=True)
|
||||
output_directory = os.path.join(files_for_moondream , "output")
|
||||
# Define your local directory where you want to save the files
|
||||
|
||||
image_encoder_cache_path = os.path.join(output_directory, "image_encoder_cache")
|
||||
class MoonDream:
|
||||
def __init__(self):
|
||||
|
||||
@@ -0,0 +1,42 @@
|
||||
# Hack: string type that is always equal in not equal comparisons
|
||||
class AnyType(str):
|
||||
def __ne__(self, __value: object) -> bool:
|
||||
return False
|
||||
|
||||
|
||||
# Our any instance wants to be a wildcard string
|
||||
any = AnyType("*")
|
||||
|
||||
|
||||
class PlayMusic:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {"required": {
|
||||
"mode": (["always", "on empty queue"], {}),
|
||||
"volume": ("FLOAT", {"min": 0, "max": 1, "step": 0.1, "default": 0.5}),
|
||||
"wave_form": ([], {"forceInput": True}),
|
||||
"sample_rate": ("INT", {"forceInput": True}),
|
||||
}}
|
||||
|
||||
FUNCTION = "nop"
|
||||
INPUT_IS_LIST = True
|
||||
OUTPUT_IS_LIST = (True,)
|
||||
OUTPUT_NODE = True
|
||||
RETURN_TYPES = (any,)
|
||||
|
||||
CATEGORY = "VLM Nodes/Audio"
|
||||
|
||||
def IS_CHANGED(self, **kwargs):
|
||||
return float("NaN")
|
||||
|
||||
def nop(self, mode, volume, wave_form, sample_rate):
|
||||
return {"ui": {"a": wave_form, "b": sample_rate}, "result": (any,)}
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"PlayMusic": PlayMusic,
|
||||
}
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"PlayMusic": "PlayMusic Node",
|
||||
}
|
||||
+257
-8
@@ -2,14 +2,19 @@ import folder_paths
|
||||
import os
|
||||
from llama_cpp import Llama, LlamaGrammar
|
||||
from .prompts import system_msg_prompts
|
||||
from pydantic import BaseModel, Field
|
||||
from pydantic import BaseModel, Field, validator
|
||||
from llama_cpp_agent.llm_agent import LlamaCppAgent
|
||||
from llama_cpp_agent.gbnf_grammar_generator.gbnf_grammar_from_pydantic_models import generate_gbnf_grammar_and_documentation
|
||||
import json
|
||||
from openai import OpenAI
|
||||
from .prompts import system_msg_prompts
|
||||
from .prompts import system_msg_simple
|
||||
from typing import List
|
||||
from typing import List, Optional
|
||||
import re
|
||||
from string import Template
|
||||
from typing import Any, List
|
||||
from pydantic import BaseModel, Field, create_model
|
||||
from typing_extensions import Literal
|
||||
|
||||
|
||||
supported_LLava_extensions = set(['.gguf'])
|
||||
|
||||
@@ -22,6 +27,14 @@ except:
|
||||
|
||||
folder_paths.folder_names_and_paths["LLavacheckpoints"] = ([os.path.join(folder_paths.models_dir, "LLavacheckpoints")], supported_LLava_extensions)
|
||||
|
||||
class AnyType(str):
|
||||
def __ne__(self, __value: object) -> bool:
|
||||
return False
|
||||
|
||||
|
||||
# Our any instance wants to be a wildcard string
|
||||
any = AnyType("*")
|
||||
|
||||
class Analysis(BaseModel):
|
||||
"""
|
||||
Represents entries about an analysis.
|
||||
@@ -50,6 +63,93 @@ class Suggestion(BaseModel):
|
||||
suggestion4 : str = Field(..., description="new Suggestion based on the inputs")
|
||||
suggestion5 : str = Field(..., description="new Suggestion based on the inputs")
|
||||
|
||||
class ArtisticTechniques(BaseModel):
|
||||
preferred: List[str] = Field(
|
||||
...,
|
||||
description="Long description of Techniques and tools favored for creating the artwork, emphasizing cutting-edge or specialized modern or traditional techniques."
|
||||
)
|
||||
|
||||
avoided: List[str] = Field(
|
||||
...,
|
||||
description="Long description of Techniques and tools favored for creating the artwork, emphasizing cutting-edge or specialized modern or traditional techniques."
|
||||
)
|
||||
|
||||
class ImageryTheme(BaseModel):
|
||||
core_subject: str = Field(
|
||||
...,
|
||||
description="Long description of Core subject or theme of the artwork, described vividly to evoke a strong image or emotion."
|
||||
)
|
||||
additional_elements: Optional[List[str]] = Field(
|
||||
default=None,
|
||||
description="Long description of Additional elements or motifs to include, enhancing the core theme with specific details or themes for a more immersive and detailed scene."
|
||||
)
|
||||
|
||||
class VisualStyle(BaseModel):
|
||||
desired: List[str] = Field(
|
||||
...,
|
||||
description="Long description of Desired visual styles and aesthetic qualities, such as realistic, stylized, or rich artwork."
|
||||
)
|
||||
undesired: List[str] = Field(
|
||||
...,
|
||||
description="Long description of Styles and aesthetic qualities to avoid."
|
||||
)
|
||||
|
||||
|
||||
class ArtInspirationNarrative(BaseModel):
|
||||
description: str
|
||||
|
||||
class ArtPromptSpecification(BaseModel):
|
||||
techniques: ArtisticTechniques
|
||||
theme: ImageryTheme
|
||||
style: VisualStyle
|
||||
creative_descriptions: List[ArtInspirationNarrative] = []
|
||||
|
||||
@validator('creative_descriptions', always=True)
|
||||
def generate_creative_descriptions(cls, v, values):
|
||||
if not values.get('techniques') or not values.get('theme') or not values.get('style'):
|
||||
return v # Ensures prerequisites are met
|
||||
|
||||
# Synthesizing the description
|
||||
technique_str = " and ".join(values['techniques'].preferred)
|
||||
theme_description = values['theme'].core_subject
|
||||
style_description = " and ".join(values['style'].desired)
|
||||
additional_elements = ", ".join(values['theme'].additional_elements) if values['theme'].additional_elements else "enriching details"
|
||||
|
||||
# Constructing the integrated creative description
|
||||
integrated_description = f"Envision an artwork that utilizes {technique_str}. The essence revolves around '{theme_description}', adorned with {additional_elements}. The visual pursuit should mirror styles such as {style_description}, bringing the concept to life with depth and emotion."
|
||||
|
||||
return [ArtInspirationNarrative(description=integrated_description)]
|
||||
|
||||
def _parse_text(text):
|
||||
lines = text.split("\n")
|
||||
lines = [line for line in lines if line != ""]
|
||||
count = 0
|
||||
for i, line in enumerate(lines):
|
||||
if "```" in line:
|
||||
count += 1
|
||||
items = line.split("`")
|
||||
if count % 2 == 1:
|
||||
lines[i] = f'<pre><code class="language-{items[-1]}">'
|
||||
else:
|
||||
lines[i] = f"<br></code></pre>"
|
||||
else:
|
||||
if i > 0:
|
||||
if count % 2 == 1:
|
||||
line = line.replace("`", r"\`")
|
||||
line = line.replace("<", "<")
|
||||
line = line.replace(">", ">")
|
||||
line = line.replace(" ", " ")
|
||||
line = line.replace("*", "*")
|
||||
line = line.replace("_", "_")
|
||||
line = line.replace("-", "-")
|
||||
line = line.replace(".", ".")
|
||||
line = line.replace("!", "!")
|
||||
line = line.replace("(", "(")
|
||||
line = line.replace(")", ")")
|
||||
line = line.replace("$", "$")
|
||||
lines[i] = "<br>" + line
|
||||
text = "".join(lines)
|
||||
return text
|
||||
class PromptGenerateAPI:
|
||||
def __init__(self):
|
||||
pass
|
||||
@@ -103,7 +203,7 @@ class PromptGenerateAPI:
|
||||
CATEGORY = "VLM Nodes/LLM"
|
||||
|
||||
def generate_prompt(self, model_name, chat_type, api_key, description, question):
|
||||
|
||||
from openai import OpenAI
|
||||
if chat_type == True:
|
||||
system_msg = system_msg_prompts
|
||||
elif chat_type == False:
|
||||
@@ -247,7 +347,60 @@ class LLMSampler:
|
||||
)
|
||||
return (f"{response['choices'][0]['message']['content']}", )
|
||||
|
||||
# Example output model
|
||||
class ChatMusician:
|
||||
def __init__(self):
|
||||
pass
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"prompt": ("STRING",{"forceInput": True,"default": ""}),
|
||||
"model": ("CUSTOM", {"default": ""}),
|
||||
"max_tokens": ("INT", {"default": 512, "min": 1, "max": 2048, "step": 1}),
|
||||
"temperature": ("FLOAT", {"default": 0.2, "min": 0.01, "max": 1.0, "step": 0.01}),
|
||||
"top_p": ("FLOAT", {"default": 0.90, "min": 0.1, "max": 1.0, "step": 0.01}),
|
||||
"top_k": ("INT", {"default": 40, "step": 1}),
|
||||
"frequency_penalty": ("FLOAT", {"default": 0.0, "step": 0.01}),
|
||||
"presence_penalty": ("FLOAT", {"default": 0.0, "step": 0.01}),
|
||||
"repeat_penalty": ("FLOAT", {"default": 1.1, "step": 0.01}),
|
||||
"seed": ("INT", {"default": 42, "step": 1}),
|
||||
"sample_rate": ("INT", {"default": 44100, "min": 8000, "max": 48000, "step": 1}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_NAMES = ("response", "wave_form", "sample_rate", )
|
||||
RETURN_TYPES = ("STRING", any, "INT", )
|
||||
FUNCTION = "chat_musician"
|
||||
CATEGORY = "VLM Nodes/Audio"
|
||||
OUTPUT_NODE = True
|
||||
|
||||
def chat_musician(self, prompt, model, max_tokens, temperature, top_p, top_k, frequency_penalty, presence_penalty, repeat_penalty, seed, sample_rate):
|
||||
llm = model
|
||||
prompt = _parse_text(prompt)
|
||||
prompt_template = Template("Human: ${inst} </s> Assistant: ")
|
||||
prompt = prompt_template.safe_substitute({"inst": prompt})
|
||||
response = llm.create_chat_completion(messages=[
|
||||
{"role": "user", "content": f"Human: {prompt} </s> Assistant: "},
|
||||
],
|
||||
max_tokens=max_tokens,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
top_k=top_k,
|
||||
frequency_penalty=frequency_penalty,
|
||||
presence_penalty=presence_penalty,
|
||||
repeat_penalty=repeat_penalty,
|
||||
seed=seed
|
||||
)
|
||||
|
||||
from symusic import Score, Synthesizer
|
||||
|
||||
abc_pattern = r'(X:\d+\n(?:[^\n]*\n)+)'
|
||||
abc_notation = re.findall(abc_pattern, f"{response['choices'][0]['message']['content']}\n")[0]
|
||||
s = Score.from_abc(abc_notation)
|
||||
audio = Synthesizer().render(s, stereo=True).tolist()[0]
|
||||
|
||||
return (abc_notation, audio, sample_rate, )
|
||||
|
||||
class KeywordExtraction:
|
||||
def __init__(self):
|
||||
@@ -304,7 +457,35 @@ class LLavaPromptGenerator:
|
||||
system_prompt="You are an advanced AI, tasked to create JSON database entries for creative long prompts for image generation. \n\n\n" + documentation)
|
||||
response = wrapped_model.get_chat_response(prompt, temperature=temperature, grammar=grammar, max_tokens=512, repeat_penalty=1.1)
|
||||
return (f"{response}", )
|
||||
|
||||
class CreativeArtPromptGenerator:
|
||||
def __init__(self):
|
||||
pass
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"prompt": ("STRING",{"forceInput": True,"default": ""}),
|
||||
"model": ("CUSTOM", {"default": ""}),
|
||||
"temperature": ("FLOAT", {"default": 0.15, "min": 0.01, "max": 1.0, "step": 0.01}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "create_creative_art_prompts"
|
||||
CATEGORY = "VLM Nodes/LLM"
|
||||
|
||||
def create_creative_art_prompts(self, prompt, model, temperature):
|
||||
gbnf_grammar, documentation = generate_gbnf_grammar_and_documentation([ArtPromptSpecification])
|
||||
grammar = LlamaGrammar.from_string(gbnf_grammar, verbose=False)
|
||||
|
||||
wrapped_model = LlamaCppAgent(model, debug_output=True,
|
||||
system_prompt="You are an advanced AI, tasked to create JSON database entries for creative description for image generation. \n\n\n" + documentation)
|
||||
response = wrapped_model.get_chat_response(prompt, temperature=temperature, grammar=grammar, max_tokens=512, repeat_penalty=1.1)
|
||||
json_response = json.loads(response)
|
||||
final_response = json_response["creative_descriptions"][0]["description"]
|
||||
return (f"{final_response}", )
|
||||
|
||||
class Suggester:
|
||||
def __init__(self):
|
||||
@@ -340,6 +521,67 @@ class Suggester:
|
||||
|
||||
return (response, )
|
||||
|
||||
class PydanticAttributeSetter:
|
||||
def __init__(self):
|
||||
self.attributes = []
|
||||
|
||||
def add_attribute(self, name: str, type_: Any, description: str, categories: List[str] = None):
|
||||
if type_ == Literal and categories:
|
||||
# Instead of directly using categories, enrich the description to hint at them
|
||||
enriched_description = f"For this {description} you should choose from this categories: {', '.join(categories)}."
|
||||
enriched_description = enriched_description.replace(" ", " ")
|
||||
self.attributes.append((name, str, Field(..., description=enriched_description)))
|
||||
else:
|
||||
self.attributes.append((name, type_, Field(..., description=description)))
|
||||
|
||||
def create_model(self, model_name: str):
|
||||
return create_model(model_name, **{name: (type_, field) for name, type_, field in self.attributes})
|
||||
|
||||
class StructuredOutput:
|
||||
def __init__(self):
|
||||
pass
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"prompt": ("STRING", {"forceInput": True, "default": ""}),
|
||||
"model": ("CUSTOM", {"default": ""}),
|
||||
"temperature": ("FLOAT", {"default": 0.15, "min": 0.01, "max": 1.0, "step": 0.01}),
|
||||
"attribute_name": ("STRING", {"default": ""}),
|
||||
"attribute_type": (["str", "int", "float", "bool", "Category"], {"default": "str"}),
|
||||
"attribute_description": ("STRING", {"default": ""}),
|
||||
"categories": ("STRING", {"default": ""}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "keyword_extract"
|
||||
CATEGORY = "VLM Nodes/LLM"
|
||||
|
||||
def keyword_extract(self, prompt, model, temperature, attribute_name, attribute_type, attribute_description, categories):
|
||||
setter = PydanticAttributeSetter()
|
||||
|
||||
if attribute_type == "Category":
|
||||
categories = categories.split(",")
|
||||
setter.add_attribute(attribute_name, Literal, attribute_description, categories)
|
||||
else:
|
||||
attribute_type = eval(attribute_type)
|
||||
setter.add_attribute(attribute_name, attribute_type, attribute_description)
|
||||
|
||||
Analysis = setter.create_model("Analysis")
|
||||
|
||||
gbnf_grammar, documentation = generate_gbnf_grammar_and_documentation([Analysis])
|
||||
grammar = LlamaGrammar.from_string(gbnf_grammar, verbose=False)
|
||||
|
||||
wrapped_model = LlamaCppAgent(model, debug_output=True,
|
||||
system_prompt=f"You are an advanced AI, tasked to create JSON database entries for analysis. \n\n\n{documentation}")
|
||||
|
||||
response = wrapped_model.get_chat_response(prompt, temperature=temperature, grammar=grammar)
|
||||
parsed_response = json.loads(response)
|
||||
|
||||
return (next(iter(parsed_response.values())),)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"LLMLoader": LLMLoader,
|
||||
@@ -348,7 +590,10 @@ NODE_CLASS_MAPPINGS = {
|
||||
"KeywordExtraction": KeywordExtraction,
|
||||
"LLavaPromptGenerator": LLavaPromptGenerator,
|
||||
"Suggester": Suggester,
|
||||
"PromptGenerateAPI": PromptGenerateAPI
|
||||
"PromptGenerateAPI": PromptGenerateAPI,
|
||||
"CreativeArtPromptGenerator": CreativeArtPromptGenerator,
|
||||
"ChatMusician": ChatMusician,
|
||||
"StructuredOutput": StructuredOutput,
|
||||
}
|
||||
# A dictionary that contains the friendly/humanly readable titles for the nodes
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
@@ -358,5 +603,9 @@ NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"KeywordExtraction": "Get Keywords",
|
||||
"LLavaPromptGenerator": "LLava PromptGenerator",
|
||||
"Suggester": "Suggester",
|
||||
"PromptGenerateAPI": "API PromptGenerator"
|
||||
}
|
||||
"PromptGenerateAPI": "API PromptGenerator",
|
||||
"CreativeArtPromptGenerator": "Creative Art PromptGenerator",
|
||||
"ChatMusician": "ChatMusician",
|
||||
"StructuredOutput": "Structured Output",
|
||||
|
||||
}
|
||||
+113
@@ -0,0 +1,113 @@
|
||||
from pathlib import Path
|
||||
from transformers import AutoModel, AutoProcessor, StoppingCriteria, StoppingCriteriaList
|
||||
import torch
|
||||
from PIL import Image
|
||||
from torchvision.transforms import ToPILImage
|
||||
from huggingface_hub import snapshot_download
|
||||
import folder_paths
|
||||
# Define the directory for saving files related to uform-gen2-qwen
|
||||
files_for_uform_gen2_qwen = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for_uform_gen2_qwen"
|
||||
files_for_uform_gen2_qwen.mkdir(parents=True, exist_ok=True) # Ensure the directory exists
|
||||
|
||||
class StopOnTokens(StoppingCriteria):
|
||||
def __call__(self, input_ids: torch.LongTensor, scores: torch.FloatTensor, **kwargs) -> bool:
|
||||
stop_ids = [151645] # Define stop tokens as per your model's specifics
|
||||
for stop_id in stop_ids:
|
||||
if input_ids[0][-1] == stop_id:
|
||||
return True
|
||||
return False
|
||||
|
||||
class UformGen2QwenChat:
|
||||
def __init__(self):
|
||||
self.model_path = snapshot_download("unum-cloud/uform-gen2-qwen-500m",
|
||||
local_dir=files_for_uform_gen2_qwen,
|
||||
force_download=False, # Set to True if you always want to download, regardless of local copy
|
||||
local_files_only=False, # Set to False to allow downloading if not available locally
|
||||
local_dir_use_symlinks="auto") # or set to True/False based on your symlink preference
|
||||
self.device = "cuda:0" if torch.cuda.is_available() else "cpu"
|
||||
self.model = AutoModel.from_pretrained(self.model_path, trust_remote_code=True).to(self.device)
|
||||
self.processor = AutoProcessor.from_pretrained(self.model_path, trust_remote_code=True)
|
||||
|
||||
def chat_response(self, message, history, image_path):
|
||||
stop = StopOnTokens()
|
||||
messages = [{"role": "system", "content": "You are a helpful Assistant."}]
|
||||
|
||||
for user_msg, assistant_msg in history:
|
||||
messages.append({"role": "user", "content": user_msg})
|
||||
messages.append({"role": "assistant", "content": assistant_msg})
|
||||
|
||||
if len(messages) == 1:
|
||||
message = f" <image>{message}"
|
||||
|
||||
messages.append({"role": "user", "content": message})
|
||||
|
||||
model_inputs = self.processor.tokenizer.apply_chat_template(
|
||||
messages,
|
||||
add_generation_prompt=True,
|
||||
return_tensors="pt"
|
||||
)
|
||||
|
||||
image = Image.open(image_path) # Load image using PIL
|
||||
image_tensor = (
|
||||
self.processor.feature_extractor(image)
|
||||
.unsqueeze(0)
|
||||
)
|
||||
|
||||
attention_mask = torch.ones(
|
||||
1, model_inputs.shape[1] + self.processor.num_image_latents - 1
|
||||
)
|
||||
|
||||
model_inputs = {
|
||||
"input_ids": model_inputs,
|
||||
"images": image_tensor,
|
||||
"attention_mask": attention_mask
|
||||
}
|
||||
|
||||
model_inputs = {k: v.to(self.device) for k, v in model_inputs.items()}
|
||||
|
||||
output = self.model.generate(
|
||||
**model_inputs,
|
||||
max_new_tokens=1024,
|
||||
stopping_criteria=StoppingCriteriaList([stop])
|
||||
)
|
||||
|
||||
response_text = self.processor.tokenizer.decode(output[0], skip_special_tokens=True)
|
||||
return response_text
|
||||
|
||||
# Example of integrating UformGen2QwenChat into a node-like structure
|
||||
class UformGen2QwenNode:
|
||||
def __init__(self):
|
||||
self.chat_model = UformGen2QwenChat()
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"question": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "",
|
||||
},
|
||||
),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
|
||||
FUNCTION = "uform_gen2_qwen_chat"
|
||||
|
||||
CATEGORY = "VLM Nodes/UformGen2Qwen"
|
||||
|
||||
def uform_gen2_qwen_chat(self, image, question):
|
||||
history = [] # Example empty history
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
temp_path = files_for_uform_gen2_qwen / "temp.png"
|
||||
pil_image.save(temp_path)
|
||||
|
||||
response = self.chat_model.chat_response(question, history, temp_path)
|
||||
return (response.split("assistant\n", 1)[1], )
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"UformGen2QwenNode": UformGen2QwenNode}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"UformGen2QwenNode": "UformGen2 Qwen Node"}
|
||||
+5
-4
@@ -1,14 +1,12 @@
|
||||
openai>=0.27.8
|
||||
accelerate>=0.25.0
|
||||
huggingface-hub==0.20.1
|
||||
Pillow>=10.1.0
|
||||
transformers>=4.36.2
|
||||
huggingface-hub>=0.20.3
|
||||
transformers>=4.38.2
|
||||
torch>=2.0.1,<3.0.0
|
||||
torchvision>=0.15.2
|
||||
einops>=0.7.0
|
||||
safetensors>=0.4.1
|
||||
pillow>=9.4.0
|
||||
py-cpuinfo
|
||||
gitpython
|
||||
moviepy
|
||||
opencv-python
|
||||
@@ -19,3 +17,6 @@ pytz
|
||||
six
|
||||
cffi
|
||||
python-dateutil>=2.7.0
|
||||
diffusers
|
||||
soundfile
|
||||
symusic
|
||||
|
||||
@@ -1,5 +1,5 @@
|
||||
import { app } from "/scripts/app.js";
|
||||
import { ComfyWidgets } from "/scripts/widgets.js";
|
||||
import { app } from "../../../scripts/app.js";
|
||||
import { ComfyWidgets } from "../../../scripts/widgets.js";
|
||||
|
||||
app.registerExtension({
|
||||
name: "n.JsonToText",
|
||||
@@ -0,0 +1,54 @@
|
||||
import { app } from "../../../scripts/app.js";
|
||||
|
||||
app.registerExtension({
|
||||
name: "n.PlayMusic",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData, app) {
|
||||
if (nodeData.name === "PlayMusic") {
|
||||
console.warn("PlayMusic");
|
||||
const onExecuted = nodeType.prototype.onExecuted;
|
||||
nodeType.prototype.onExecuted = async function () {
|
||||
onExecuted?.apply(this, arguments);
|
||||
|
||||
// Check for "on empty queue" condition, if applicable
|
||||
if (this.widgets[0].value === "on empty queue") {
|
||||
if (app.ui.lastQueueSize !== 0) {
|
||||
await new Promise((r) => setTimeout(r, 500));
|
||||
}
|
||||
if (app.ui.lastQueueSize !== 0) {
|
||||
return;
|
||||
}
|
||||
}
|
||||
|
||||
// Assuming that 'arguments[0].a' is the waveform and 'arguments[0].b' is the sample rate
|
||||
let waveform = arguments[0].a; // An array of floats (-1 to 1)
|
||||
let sampleRate = arguments[0].b; // The sample rate of the audio
|
||||
console.log(waveform, sampleRate);
|
||||
// Create AudioContext
|
||||
let audioCtx = new (window.AudioContext || window.webkitAudioContext)({sampleRate: sampleRate});
|
||||
|
||||
// Create AudioBuffer
|
||||
let buffer = audioCtx.createBuffer(1, waveform[0].length, sampleRate);
|
||||
|
||||
// Fill the AudioBuffer
|
||||
buffer.getChannelData(0).set(waveform[0]);
|
||||
|
||||
// Create a source and connect it to the buffer
|
||||
let source = audioCtx.createBufferSource();
|
||||
source.buffer = buffer;
|
||||
source.connect(audioCtx.destination);
|
||||
|
||||
// Set volume, if applicable. Assuming the volume is the second widget's value.
|
||||
let volume = this.widgets[1].value;
|
||||
if (volume !== undefined) {
|
||||
let gainNode = audioCtx.createGain();
|
||||
gainNode.gain.value = volume;
|
||||
source.connect(gainNode);
|
||||
gainNode.connect(audioCtx.destination);
|
||||
}
|
||||
|
||||
// Play the sound
|
||||
source.start();
|
||||
};
|
||||
}
|
||||
},
|
||||
});
|
||||
@@ -1,5 +1,5 @@
|
||||
import { app } from "/scripts/app.js";
|
||||
import { ComfyWidgets } from "/scripts/widgets.js";
|
||||
import { app } from "../../../scripts/app.js";
|
||||
import { ComfyWidgets } from "../../../scripts/widgets.js";
|
||||
|
||||
app.registerExtension({
|
||||
name: "n.ViewText",
|
||||
Reference in New Issue
Block a user