Merge main branch.
Former-commit-id: 800ca74fad0d9021f1e96ddf32cd93cdb37cbbe0
This commit is contained in:
 sennnnn
@@ -3,7 +3,7 @@
|
||||
[[Project Page]](https://pku-yuangroup.github.io/Open-Sora-Plan/) [[中文主页]](https://pku-yuangroup.github.io/Open-Sora-Plan/blog_cn.html)
|
||||
|
||||
[](https://discord.gg/fqpmStRX)
|
||||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/issues/53#issuecomment-1980312563)
|
||||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/issues/53#issuecomment-1987226516)
|
||||
[](https://x.com/LinBin46984/status/1763476690385424554?s=20) <br>
|
||||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/blob/main/LICENSE)
|
||||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/graphs/contributors)
|
||||
@@ -42,6 +42,8 @@ Project stages:
|
||||
|
||||
|
||||
## 📰 News
|
||||
**[2024.03.10]** 🚀🚀🚀 This repo supports training a latent size of 225×90×90 (t×h×w), which means we are able to **train 1 minute of 1080P video with 30FPS** (2× interpolated frames and 2× super resolution) under class-condition.
|
||||
|
||||
**[2024.03.08]** We support the training code of text condition with 16 frames of 512x512. The code is mainly borrowed from [Latte](https://github.com/Vchitect/Latte).
|
||||
|
||||
**[2024.03.07]** We support training with 128 frames (when sample rate = 3, which is about 13 seconds) of 256x256, or 64 frames (which is about 6 seconds) of 512x512.
|
||||
@@ -78,9 +80,10 @@ Project stages:
|
||||
- [x] Add evaluation scripts (FVD, CLIP score). 🤝 Thanks to [@rain305f](https://github.com/rain305f)
|
||||
|
||||
#### Train models that boost resolution and duration
|
||||
- [ ] Add [PI](https://arxiv.org/abs/2306.15595) to support out-of-domain size. 🙏 **[Need your contribution]**
|
||||
- [ ] Add 2D RoPE to improve generalization ability as [FiT](https://github.com/whlzy/FiT). 🙏 **[Need your contribution]**
|
||||
- [ ] Train a **low dimension** Video-AE, whether it is VAE or VQVAE. 🚀 **[Require more computation]**
|
||||
- [x] Add [PI](https://arxiv.org/abs/2306.15595) to support out-of-domain size. 🤝 Thanks to [@jpthu17](https://github.com/jpthu17)
|
||||
- [x] Add 2D RoPE to improve generalization ability as [FiT](https://github.com/whlzy/FiT). 🤝 Thanks to [@jpthu17](https://github.com/jpthu17)
|
||||
- [ ] Compress KV according to [PixArt-sigma](https://pixart-alpha.github.io/PixArt-sigma-project). ⌛ [WIP]
|
||||
- [ ] Train a **low dimension** Video-AE, whether it is VAE or VQVAE. ⌛ [WIP] 🚀 **[Require more computation]**
|
||||
- [x] Extract offline feature.
|
||||
- [x] Train with offline feature.
|
||||
- [x] Add frame interpolation model. 🤝 Thanks to [@yunyangge](https://github.com/yunyangge)
|
||||
@@ -113,7 +116,7 @@ Project stages:
|
||||
- [x] Support mixed precision training.
|
||||
- [x] Add gradient checkpoint.
|
||||
- [x] Support for ReBased and Ring attention. 🤝 Thanks to [@kabachuha](https://github.com/kabachuha)
|
||||
- [ ] Train using the deepspeed engine. 🙏 **[Need your contribution]**
|
||||
- [x] Train using the deepspeed engine. 🤝 Thanks to [@sennnnn](https://github.com/sennnnn)
|
||||
- [ ] Integrate with [Colossal-AI](https://github.com/PKU-YuanGroup/Open-Sora-Plan/issues/59#issue-2170735221) for a cheaper, faster, and more efficient. 🙏 **[Need your contribution]**
|
||||
- [ ] Train with a text condition. Here we could conduct different experiments:
|
||||
- [ ] Train with T5 conditioning. 🚀 **[Require more computation]**
|
||||
@@ -156,22 +159,23 @@ Project stages:
|
||||
|
||||
## 🛠️ Requirements and Installation
|
||||
|
||||
The requirements are as follows.
|
||||
|
||||
* Python >= 3.8
|
||||
* CUDA Version >= 11.7
|
||||
* Install required packages
|
||||
|
||||
1. Clone this repository and navigate to Open-Sora-Plan folder
|
||||
```
|
||||
git clone https://github.com/PKU-YuanGroup/Open-Sora-Plan
|
||||
cd Open-Sora-Plan
|
||||
```
|
||||
2. Install required packages
|
||||
```
|
||||
conda create -n opensora python=3.8 -y
|
||||
conda activate opensora
|
||||
pip install -e .
|
||||
```
|
||||
|
||||
* Install optional requirements such as static type checking:
|
||||
|
||||
3. Install additional packages for training cases
|
||||
```
|
||||
pip install -e ".[train]"
|
||||
pip install flash-attn --no-build-isolation
|
||||
```
|
||||
4. Install optional requirements such as static type checking:
|
||||
```
|
||||
pip install -e '.[dev]'
|
||||
```
|
||||
@@ -268,9 +272,9 @@ For more details, please refer to the [Contribution Guidelines](docs/Contributio
|
||||
## 🔒 License
|
||||
* The service is a research preview intended for non-commercial use only. See [LICENSE](LICENSE) for details.
|
||||
|
||||
|
||||
<!--
|
||||
## ✨ Star History
|
||||
|
||||
[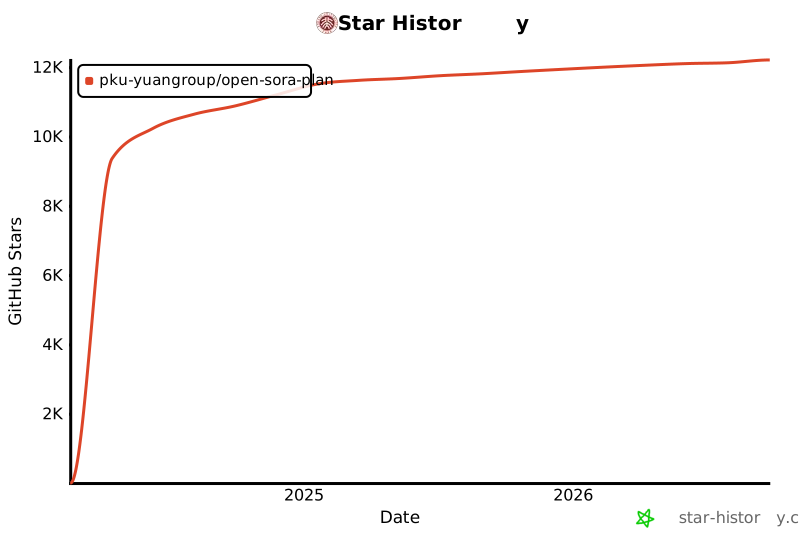](https://star-history.com/#PKU-YuanGroup/Open-Sora-Plan&Date)
|
||||
|
||||
-->
|
||||
|
||||
|
||||
@@ -1,6 +1,7 @@
|
||||
from .dit.dit import DiT_models
|
||||
from .latte.latte import Latte_models
|
||||
from .latte_t2v.latte_t2v import LatteT2V
|
||||
from .latte.modeling_latte import Latte_models
|
||||
# from .latte.latte import Latte_models
|
||||
from .latte_t2v.latte_t2v import LatteT2V
|
||||
|
||||
Diffusion_models = {}
|
||||
Diffusion_models.update(DiT_models)
|
||||
|
||||
@@ -0,0 +1,89 @@
|
||||
# This source code is licensed under the license found in the
|
||||
# LICENSE file in the root directory of this source tree.
|
||||
# --------------------------------------------------------
|
||||
# References:
|
||||
# EVA: https://github.com/baaivision/EVA
|
||||
# Transformer升级之路:2、博采众长的旋转式位置编码: https://spaces.ac.cn/archives/8265
|
||||
# Transformer升级之路:4、二维位置的旋转式位置编码: https://spaces.ac.cn/archives/8397
|
||||
# --------------------------------------------------------
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from math import pi
|
||||
from einops import rearrange, repeat
|
||||
|
||||
|
||||
def broadcat(tensors, dim=-1):
|
||||
num_tensors = len(tensors)
|
||||
shape_lens = set(list(map(lambda t: len(t.shape), tensors)))
|
||||
assert len(shape_lens) == 1, 'tensors must all have the same number of dimensions'
|
||||
shape_len = list(shape_lens)[0]
|
||||
dim = (dim + shape_len) if dim < 0 else dim
|
||||
dims = list(zip(*map(lambda t: list(t.shape), tensors)))
|
||||
expandable_dims = [(i, val) for i, val in enumerate(dims) if i != dim]
|
||||
assert all([*map(lambda t: len(set(t[1])) <= 2, expandable_dims)]), 'invalid dimensions for broadcastable concatentation'
|
||||
max_dims = list(map(lambda t: (t[0], max(t[1])), expandable_dims))
|
||||
expanded_dims = list(map(lambda t: (t[0], (t[1],) * num_tensors), max_dims))
|
||||
expanded_dims.insert(dim, (dim, dims[dim]))
|
||||
expandable_shapes = list(zip(*map(lambda t: t[1], expanded_dims)))
|
||||
tensors = list(map(lambda t: t[0].expand(*t[1]), zip(tensors, expandable_shapes)))
|
||||
return torch.cat(tensors, dim=dim)
|
||||
|
||||
|
||||
def rotate_half(x):
|
||||
x = rearrange(x, '... (d r) -> ... d r', r=2)
|
||||
x1, x2 = x.unbind(dim=-1)
|
||||
x = torch.stack((-x2, x1), dim=-1)
|
||||
return rearrange(x, '... d r -> ... (d r)')
|
||||
|
||||
|
||||
class VisionRotaryEmbeddingFast(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
dim,
|
||||
pt_hw=(int, int), # (H, W)
|
||||
ft_hw=None,
|
||||
custom_freqs = None,
|
||||
freqs_for = 'lang',
|
||||
theta = 10000,
|
||||
max_freq = 10,
|
||||
num_freqs = 1,
|
||||
):
|
||||
super().__init__()
|
||||
# Unlike a 1d RoPE, a 2d RoPE requires splitting the dimension into four parts
|
||||
# References: https://spaces.ac.cn/archives/8397
|
||||
|
||||
if custom_freqs:
|
||||
freqs = custom_freqs
|
||||
elif freqs_for == 'lang':
|
||||
freqs = 1. / (theta ** (torch.arange(0, dim, 2)[:(dim // 2)].float() / dim))
|
||||
elif freqs_for == 'pixel':
|
||||
freqs = torch.linspace(1., max_freq / 2, dim // 2) * pi
|
||||
elif freqs_for == 'constant':
|
||||
freqs = torch.ones(num_freqs).float()
|
||||
else:
|
||||
raise ValueError(f'unknown modality {freqs_for}')
|
||||
|
||||
if ft_hw is None: ft_hw = pt_hw
|
||||
h_t = torch.arange(ft_hw[0]) / ft_hw[0] * pt_hw[0]
|
||||
w_t = torch.arange(ft_hw[1]) / ft_hw[1] * pt_hw[1]
|
||||
|
||||
h_freqs = torch.einsum('..., f -> ... f', h_t, freqs)
|
||||
w_freqs = torch.einsum('..., f -> ... f', w_t, freqs)
|
||||
|
||||
h_freqs = repeat(h_freqs, '... n -> ... (n r)', r=2)
|
||||
w_freqs = repeat(w_freqs, '... n -> ... (n r)', r=2)
|
||||
|
||||
freqs = broadcat((h_freqs[:, None, :], w_freqs[None, :, :]), dim=-1)
|
||||
freqs_cos = freqs.cos().view(-1, freqs.shape[-1])
|
||||
freqs_sin = freqs.sin().view(-1, freqs.shape[-1])
|
||||
|
||||
self.register_buffer("freqs_cos", freqs_cos)
|
||||
self.register_buffer("freqs_sin", freqs_sin)
|
||||
|
||||
def forward(self, t):
|
||||
# 2d RoPE: [[cos(h*theta), -sin(h*theta), 0, 0 ],
|
||||
# [sin(h*theta), cos(h*theta), 0, 0 ],
|
||||
# [0, 0, cos(w*theta), -sin(w*theta)],
|
||||
# [0, 0, sin(w*theta), cos(w*theta) ],]
|
||||
|
||||
return t * self.freqs_cos + rotate_half(t) * self.freqs_sin
|
||||
@@ -5,7 +5,7 @@
|
||||
# GLIDE: https://github.com/openai/glide-text2im
|
||||
# MAE: https://github.com/facebookresearch/mae/blob/main/models_mae.py
|
||||
# --------------------------------------------------------
|
||||
from typing import Final, Optional
|
||||
from typing import Final, Optional, Tuple, Union
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
@@ -17,13 +17,8 @@ from timm.layers import use_fused_attn, to_2tuple
|
||||
# from timm.models.vision_transformer import PatchEmbed, Attention, Mlp
|
||||
from timm.models.vision_transformer import PatchEmbed, Mlp
|
||||
from torch.nn import functional as F
|
||||
|
||||
# the xformers lib allows less memory, faster training and inference
|
||||
try:
|
||||
import xformers
|
||||
import xformers.ops
|
||||
except:
|
||||
XFORMERS_IS_AVAILBLE = False
|
||||
from .VisionRoPE import VisionRotaryEmbeddingFast
|
||||
from torch.nn import functional as F
|
||||
|
||||
try:
|
||||
# needs to have https://github.com/corl-team/rebased/ installed
|
||||
@@ -50,7 +45,11 @@ class Attention(nn.Module):
|
||||
attn_drop: float = 0.,
|
||||
proj_drop: float = 0.,
|
||||
norm_layer: nn.Module = nn.LayerNorm,
|
||||
attention_mode='math'
|
||||
attention_mode='math',
|
||||
attention_pe_mode=None,
|
||||
hw: Union[int, Tuple[int, int]] = 16, # (h, w)
|
||||
pt_hw: Union[int, Tuple[int, int]] = 16, # (h, w)
|
||||
intp_vfreq: bool = True, # vision position interpolation
|
||||
) -> None:
|
||||
super().__init__()
|
||||
assert dim % num_heads == 0, 'dim should be divisible by num_heads'
|
||||
@@ -58,6 +57,7 @@ class Attention(nn.Module):
|
||||
self.head_dim = dim // num_heads
|
||||
self.scale = self.head_dim ** -0.5
|
||||
self.attention_mode = attention_mode
|
||||
self.attention_pe_mode = attention_pe_mode
|
||||
|
||||
self.qkv = nn.Linear(dim, dim * 3, bias=qkv_bias)
|
||||
self.q_norm = norm_layer(self.head_dim) if qk_norm else nn.Identity()
|
||||
@@ -66,29 +66,52 @@ class Attention(nn.Module):
|
||||
self.proj = nn.Linear(dim, dim)
|
||||
self.proj_drop = nn.Dropout(proj_drop)
|
||||
|
||||
def forward(self, x: torch.Tensor, attention_mask) -> torch.Tensor:
|
||||
if self.attention_pe_mode == '2d_rope':
|
||||
half_head_dim = dim // num_heads // 2
|
||||
self.hw = to_2tuple(hw)
|
||||
self.rope = VisionRotaryEmbeddingFast(
|
||||
dim=half_head_dim,
|
||||
pt_hw=to_2tuple(pt_hw),
|
||||
ft_hw=self.hw if intp_vfreq else None,
|
||||
)
|
||||
|
||||
def forward(self, x: torch.Tensor, attn_mask) -> torch.Tensor:
|
||||
B, N, C = x.shape
|
||||
qkv = self.qkv(x).reshape(B, N, 3, self.num_heads, C // self.num_heads).permute(2, 0, 3, 1, 4).contiguous()
|
||||
q, k, v = qkv.unbind(0) # make torchscript happy (cannot use tensor as tuple) b h n c
|
||||
if attn_mask is not None:
|
||||
attn_mask = attn_mask.repeat(1, self.num_heads, 1, 1).to(q.dtype)
|
||||
|
||||
if self.attention_mode == 'xformers': # cause loss nan while using with amp
|
||||
assert q.ndim == 4 and (attention_mask is None or torch.all(attention_mask.bool()))
|
||||
q, k, v = q.transpose(1, 2), k.transpose(1, 2), v.transpose(1, 2)
|
||||
x = xformers.ops.memory_efficient_attention(q, k, v, p=self.attn_drop.p, scale=self.scale).reshape(B, N, C)
|
||||
if self.attention_pe_mode == '2d_rope':
|
||||
q_t = q.view(B, self.num_heads, -1, self.hw[0] * self.hw[1], C // self.num_heads)
|
||||
ro_q_t = self.rope(q_t)
|
||||
q = ro_q_t.view(B, self.num_heads, N, C // self.num_heads)
|
||||
|
||||
elif self.attention_mode == 'flash':
|
||||
assert attention_mask is None or torch.all(attention_mask.bool())
|
||||
# cause loss nan while using with amp
|
||||
# Optionally use the context manager to ensure one of the fused kerenels is run
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False, enable_flash=True, enable_mem_efficient=False):
|
||||
x = torch.nn.functional.scaled_dot_product_attention(q, k, v, dropout_p=self.attn_drop.p,
|
||||
scale=self.scale).reshape(B, N,
|
||||
C) # require pytorch 2.0
|
||||
k_t = k.view(B, self.num_heads, -1, self.hw[0] * self.hw[1], C // self.num_heads)
|
||||
ro_k_t = self.rope(k_t)
|
||||
k = ro_k_t.view(B, self.num_heads, N, C // self.num_heads)
|
||||
|
||||
if self.attention_mode == 'xformers': # require pytorch 2.0
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False, enable_flash=False, enable_mem_efficient=True):
|
||||
x = F.scaled_dot_product_attention(q, k, v, attn_mask=attn_mask,
|
||||
dropout_p=self.attn_drop.p, scale=self.scale).reshape(B, N, C)
|
||||
|
||||
elif self.attention_mode == 'flash': # require pytorch 2.0
|
||||
# https://github.com/PKU-YuanGroup/Open-Sora-Plan/issues/109
|
||||
if attn_mask is None or torch.all(attn_mask.bool()):
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False, enable_flash=True, enable_mem_efficient=False):
|
||||
x = F.scaled_dot_product_attention(q, k, v,
|
||||
dropout_p=self.attn_drop.p, scale=self.scale).reshape(B, N, C)
|
||||
else: # turn to xformers
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False, enable_flash=False, enable_mem_efficient=True):
|
||||
x = F.scaled_dot_product_attention(q, k, v, attn_mask=attn_mask,
|
||||
dropout_p=self.attn_drop.p, scale=self.scale).reshape(B, N, C)
|
||||
|
||||
elif self.attention_mode == 'math':
|
||||
attn = (q @ k.transpose(-2, -1)) * self.scale
|
||||
if attention_mask is not None:
|
||||
attn = attn + attention_mask
|
||||
if attn_mask is not None:
|
||||
attn_bias = self.make_attn_bias(attn_mask)
|
||||
attn = attn + attn_bias
|
||||
attn = attn.softmax(dim=-1)
|
||||
if torch.any(torch.isnan(attn)):
|
||||
print('torch.any(torch.isnan(attn))')
|
||||
@@ -109,6 +132,12 @@ class Attention(nn.Module):
|
||||
x = self.proj_drop(x)
|
||||
return x
|
||||
|
||||
def make_attn_bias(self, attn_mask):
|
||||
# The numerical range of bfloat16, float16 can't conver -1e8
|
||||
# Refer to https://discuss.pytorch.org/t/runtimeerror-value-cannot-be-converted-to-type-at-half-without-overflow-1e-30/109768
|
||||
attn_bias = torch.where(attn_mask == 0, -1e8 if attn_mask.dtype == torch.float32 else -1e4, attn_mask)
|
||||
attn_bias = torch.where(attn_mask == 1, 0., attn_bias)
|
||||
return attn_bias
|
||||
|
||||
def modulate(x, shift, scale):
|
||||
return x * (1 + scale.unsqueeze(1)) + shift.unsqueeze(1)
|
||||
@@ -256,6 +285,9 @@ class DiT(nn.Module):
|
||||
learn_sigma=True,
|
||||
extras=1,
|
||||
attention_mode='math',
|
||||
attention_pe_mode=None,
|
||||
pt_input_size: Union[int, Tuple[int, int]] = None, # (h, w)
|
||||
intp_vfreq: bool = True, # vision position interpolation
|
||||
):
|
||||
super().__init__()
|
||||
self.gradient_checkpointing = False
|
||||
@@ -279,8 +311,12 @@ class DiT(nn.Module):
|
||||
self.pos_embed = nn.Parameter(torch.zeros(1, num_patches, hidden_size), requires_grad=False)
|
||||
self.temp_embed = nn.Parameter(torch.zeros(1, num_frames, hidden_size), requires_grad=False)
|
||||
|
||||
if pt_input_size is None:
|
||||
pt_input_size = input_size
|
||||
self.blocks = nn.ModuleList([
|
||||
DiTBlock(hidden_size, num_heads, mlp_ratio=mlp_ratio, attention_mode=attention_mode) for _ in range(depth)
|
||||
DiTBlock(hidden_size, num_heads, mlp_ratio=mlp_ratio, attention_mode=attention_mode,
|
||||
attention_pe_mode=attention_pe_mode, hw=input_size, pt_hw=pt_input_size,
|
||||
intp_vfreq=intp_vfreq) for _ in range(depth)
|
||||
])
|
||||
self.final_layer = FinalLayer(hidden_size, patch_size_t, patch_size, self.out_channels)
|
||||
self.initialize_weights()
|
||||
@@ -346,15 +382,13 @@ class DiT(nn.Module):
|
||||
return outputs
|
||||
return ckpt_forward
|
||||
|
||||
def make_mask(self, attention_mask, dtype):
|
||||
def make_mask(self, attention_mask):
|
||||
attention_mask = attention_mask.flatten(1).unsqueeze(-1) # bs t h w -> bs thw 1
|
||||
attention_mask = attention_mask @ attention_mask.transpose(1, 2) # bs thw 1 @ bs 1 thw = bs thw thw
|
||||
attention_mask = attention_mask.unsqueeze(1)
|
||||
# attention_mask = attention_mask.masked_fill(attention_mask == 0, torch.finfo(dtype).min)
|
||||
attention_mask = attention_mask.masked_fill(attention_mask == 0, 1e-8)
|
||||
return attention_mask
|
||||
|
||||
def forward(self, x, t, y, attention_mask=None, use_fp16=False):
|
||||
def forward(self, x, t, y, attention_mask=None):
|
||||
"""
|
||||
Forward pass of DiT.
|
||||
x: (B, T, C, H, W) tensor of spatial inputs (images or latent representations of images)
|
||||
@@ -367,7 +401,7 @@ class DiT(nn.Module):
|
||||
B, T, C, H, W = x.shape
|
||||
self.t = T // self.patch_size_t # 4 // 1
|
||||
if attention_mask is not None:
|
||||
attention_mask = self.make_mask(attention_mask, x.dtype)
|
||||
attention_mask = self.make_mask(attention_mask)
|
||||
|
||||
|
||||
|
||||
@@ -522,4 +556,4 @@ DiT_models = {
|
||||
'DiT-L/122': DiT_L_122, 'DiT-L/144': DiT_L_144, 'DiT-L/188': DiT_L_188,
|
||||
'DiT-B/122': DiT_B_122, 'DiT-B/144': DiT_B_144, 'DiT-B/188': DiT_B_188,
|
||||
'DiT-S/122': DiT_S_122, 'DiT-S/144': DiT_S_144, 'DiT-S/188': DiT_S_188,
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,89 @@
|
||||
# This source code is licensed under the license found in the
|
||||
# LICENSE file in the root directory of this source tree.
|
||||
# --------------------------------------------------------
|
||||
# References:
|
||||
# EVA: https://github.com/baaivision/EVA
|
||||
# Transformer升级之路:2、博采众长的旋转式位置编码: https://spaces.ac.cn/archives/8265
|
||||
# Transformer升级之路:4、二维位置的旋转式位置编码: https://spaces.ac.cn/archives/8397
|
||||
# --------------------------------------------------------
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from math import pi
|
||||
from einops import rearrange, repeat
|
||||
|
||||
|
||||
def broadcat(tensors, dim=-1):
|
||||
num_tensors = len(tensors)
|
||||
shape_lens = set(list(map(lambda t: len(t.shape), tensors)))
|
||||
assert len(shape_lens) == 1, 'tensors must all have the same number of dimensions'
|
||||
shape_len = list(shape_lens)[0]
|
||||
dim = (dim + shape_len) if dim < 0 else dim
|
||||
dims = list(zip(*map(lambda t: list(t.shape), tensors)))
|
||||
expandable_dims = [(i, val) for i, val in enumerate(dims) if i != dim]
|
||||
assert all([*map(lambda t: len(set(t[1])) <= 2, expandable_dims)]), 'invalid dimensions for broadcastable concatentation'
|
||||
max_dims = list(map(lambda t: (t[0], max(t[1])), expandable_dims))
|
||||
expanded_dims = list(map(lambda t: (t[0], (t[1],) * num_tensors), max_dims))
|
||||
expanded_dims.insert(dim, (dim, dims[dim]))
|
||||
expandable_shapes = list(zip(*map(lambda t: t[1], expanded_dims)))
|
||||
tensors = list(map(lambda t: t[0].expand(*t[1]), zip(tensors, expandable_shapes)))
|
||||
return torch.cat(tensors, dim=dim)
|
||||
|
||||
|
||||
def rotate_half(x):
|
||||
x = rearrange(x, '... (d r) -> ... d r', r=2)
|
||||
x1, x2 = x.unbind(dim=-1)
|
||||
x = torch.stack((-x2, x1), dim=-1)
|
||||
return rearrange(x, '... d r -> ... (d r)')
|
||||
|
||||
|
||||
class VisionRotaryEmbeddingFast(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
dim,
|
||||
pt_hw=(int, int), # (H, W)
|
||||
ft_hw=None,
|
||||
custom_freqs = None,
|
||||
freqs_for = 'lang',
|
||||
theta = 10000,
|
||||
max_freq = 10,
|
||||
num_freqs = 1,
|
||||
):
|
||||
super().__init__()
|
||||
# Unlike a 1d RoPE, a 2d RoPE requires splitting the dimension into four parts
|
||||
# References: https://spaces.ac.cn/archives/8397
|
||||
|
||||
if custom_freqs:
|
||||
freqs = custom_freqs
|
||||
elif freqs_for == 'lang':
|
||||
freqs = 1. / (theta ** (torch.arange(0, dim, 2)[:(dim // 2)].float() / dim))
|
||||
elif freqs_for == 'pixel':
|
||||
freqs = torch.linspace(1., max_freq / 2, dim // 2) * pi
|
||||
elif freqs_for == 'constant':
|
||||
freqs = torch.ones(num_freqs).float()
|
||||
else:
|
||||
raise ValueError(f'unknown modality {freqs_for}')
|
||||
|
||||
if ft_hw is None: ft_hw = pt_hw
|
||||
h_t = torch.arange(ft_hw[0]) / ft_hw[0] * pt_hw[0]
|
||||
w_t = torch.arange(ft_hw[1]) / ft_hw[1] * pt_hw[1]
|
||||
|
||||
h_freqs = torch.einsum('..., f -> ... f', h_t, freqs)
|
||||
w_freqs = torch.einsum('..., f -> ... f', w_t, freqs)
|
||||
|
||||
h_freqs = repeat(h_freqs, '... n -> ... (n r)', r=2)
|
||||
w_freqs = repeat(w_freqs, '... n -> ... (n r)', r=2)
|
||||
|
||||
freqs = broadcat((h_freqs[:, None, :], w_freqs[None, :, :]), dim=-1)
|
||||
freqs_cos = freqs.cos().view(-1, freqs.shape[-1])
|
||||
freqs_sin = freqs.sin().view(-1, freqs.shape[-1])
|
||||
|
||||
self.register_buffer("freqs_cos", freqs_cos)
|
||||
self.register_buffer("freqs_sin", freqs_sin)
|
||||
|
||||
def forward(self, t):
|
||||
# 2d RoPE: [[cos(h*theta), -sin(h*theta), 0, 0 ],
|
||||
# [sin(h*theta), cos(h*theta), 0, 0 ],
|
||||
# [0, 0, cos(w*theta), -sin(w*theta)],
|
||||
# [0, 0, sin(w*theta), cos(w*theta) ],]
|
||||
|
||||
return t * self.freqs_cos + rotate_half(t) * self.freqs_sin
|
||||
@@ -0,0 +1,26 @@
|
||||
import json
|
||||
|
||||
"""
|
||||
We are currently working on the abstraction of the code structure,
|
||||
so there is no content here for the moment.
|
||||
It will be gradually optimized over time.
|
||||
Contributions from the open-source community are welcome.
|
||||
"""
|
||||
|
||||
|
||||
class BaseConfiguration:
|
||||
def __init__(self, **kwargs):
|
||||
pass
|
||||
|
||||
def to_json_string(self):
|
||||
json_string = json.dumps(vars(self))
|
||||
return json_string
|
||||
|
||||
def to_dict(self):
|
||||
return vars(self)
|
||||
|
||||
@classmethod
|
||||
def load_from_file(cls, config_path):
|
||||
with open(config_path, 'r') as json_file:
|
||||
config_dict = json.load(json_file)
|
||||
return cls(**config_dict)
|
||||
@@ -0,0 +1,92 @@
|
||||
from typing import Union, Tuple
|
||||
|
||||
from .configuration_base import BaseConfiguration
|
||||
|
||||
|
||||
class LatteConfiguration(BaseConfiguration):
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
input_size=32,
|
||||
patch_size=2,
|
||||
patch_size_t=1,
|
||||
in_channels=4,
|
||||
hidden_size=1152,
|
||||
depth=28,
|
||||
num_heads=16,
|
||||
mlp_ratio=4.0,
|
||||
num_frames=16,
|
||||
class_dropout_prob=0.1,
|
||||
num_classes=1000,
|
||||
learn_sigma=True,
|
||||
extras=1,
|
||||
attention_mode='math',
|
||||
attention_pe_mode=None,
|
||||
pt_input_size: Union[int, Tuple[int, int]] = None, # (h, w)
|
||||
intp_vfreq: bool = True, # vision position interpolation
|
||||
**kwargs,
|
||||
):
|
||||
super().__init__(**kwargs)
|
||||
|
||||
self.input_size = input_size
|
||||
self.patch_size = patch_size
|
||||
self.patch_size_t = patch_size_t
|
||||
self.in_channels = in_channels
|
||||
self.hidden_size = hidden_size
|
||||
self.depth = depth
|
||||
self.num_heads = num_heads
|
||||
self.mlp_ratio = mlp_ratio
|
||||
self.num_frames = num_frames
|
||||
self.class_dropout_prob = class_dropout_prob
|
||||
self.num_classes = num_classes
|
||||
self.learn_sigma = learn_sigma
|
||||
self.extras = learn_sigma
|
||||
self.attention_mode = attention_mode
|
||||
self.attention_pe_mode = attention_pe_mode
|
||||
self.pt_input_size = pt_input_size
|
||||
self.intp_vfreq = intp_vfreq
|
||||
|
||||
|
||||
def Latte_XL_122_Config(**kwargs):
|
||||
return LatteConfiguration(depth=28, hidden_size=1152, patch_size_t=1, patch_size=2, num_heads=16, **kwargs)
|
||||
|
||||
def Latte_XL_144_Config(**kwargs):
|
||||
return LatteConfiguration(depth=28, hidden_size=1152, patch_size_t=1, patch_size=4, num_heads=16, **kwargs)
|
||||
|
||||
def Latte_XL_188_Config(**kwargs):
|
||||
return LatteConfiguration(depth=28, hidden_size=1152, patch_size_t=1, patch_size=8, num_heads=16, **kwargs)
|
||||
|
||||
def Latte_L_122_Config(**kwargs):
|
||||
return LatteConfiguration(depth=24, hidden_size=1024, patch_size_t=1, patch_size=2, num_heads=16, **kwargs)
|
||||
|
||||
def Latte_L_144_Config(**kwargs):
|
||||
return LatteConfiguration(depth=24, hidden_size=1024, patch_size_t=1, patch_size=4, num_heads=16, **kwargs)
|
||||
|
||||
def Latte_L_188_Config(**kwargs):
|
||||
return LatteConfiguration(depth=24, hidden_size=1024, patch_size_t=1, patch_size=8, num_heads=16, **kwargs)
|
||||
|
||||
def Latte_B_122_Config(**kwargs):
|
||||
return LatteConfiguration(depth=12, hidden_size=768, patch_size_t=1, patch_size=2, num_heads=12, **kwargs)
|
||||
|
||||
def Latte_B_144_Config(**kwargs):
|
||||
return LatteConfiguration(depth=12, hidden_size=768, patch_size_t=1, patch_size=4, num_heads=12, **kwargs)
|
||||
|
||||
def Latte_B_188_Config(**kwargs):
|
||||
return LatteConfiguration(depth=12, hidden_size=768, patch_size_t=1, patch_size=8, num_heads=12, **kwargs)
|
||||
|
||||
def Latte_S_122_Config(**kwargs):
|
||||
return LatteConfiguration(depth=12, hidden_size=384, patch_size_t=1, patch_size=2, num_heads=6, **kwargs)
|
||||
|
||||
def Latte_S_144_Config(**kwargs):
|
||||
return LatteConfiguration(depth=12, hidden_size=384, patch_size_t=1, patch_size=4, num_heads=6, **kwargs)
|
||||
|
||||
def Latte_S_188_Config(**kwargs):
|
||||
return LatteConfiguration(depth=12, hidden_size=384, patch_size_t=1, patch_size=8, num_heads=6, **kwargs)
|
||||
|
||||
|
||||
Latte_configs = {
|
||||
"Latte-XL/122": Latte_XL_122_Config, "Latte-XL/144": Latte_XL_144_Config, "Latte-XL/188": Latte_XL_188_Config,
|
||||
"Latte-L/122": Latte_L_122_Config, "Latte-L/144": Latte_L_144_Config, "Latte-L/188": Latte_L_188_Config,
|
||||
"Latte-B/122": Latte_B_122_Config, "Latte-B/144": Latte_B_144_Config, "Latte-B/188": Latte_B_188_Config,
|
||||
"Latte-S/122": Latte_S_122_Config, "Latte-S/144": Latte_S_144_Config, "Latte-S/188": Latte_S_188_Config,
|
||||
}
|
||||
@@ -11,21 +11,13 @@ import math
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import numpy as np
|
||||
|
||||
from .VisionRoPE import VisionRotaryEmbeddingFast
|
||||
from einops import rearrange, repeat
|
||||
from timm.models.vision_transformer import Mlp, PatchEmbed
|
||||
|
||||
from typing import Tuple, Union
|
||||
from timm.layers import to_2tuple
|
||||
import torch.utils.checkpoint as cp
|
||||
|
||||
# for i in sys.path:
|
||||
# print(i)
|
||||
|
||||
# the xformers lib allows less memory, faster training and inference
|
||||
try:
|
||||
import xformers
|
||||
import xformers.ops
|
||||
except:
|
||||
XFORMERS_IS_AVAILBLE = False
|
||||
from torch.nn import functional as F
|
||||
|
||||
try:
|
||||
# needs to have https://github.com/corl-team/rebased/ installed
|
||||
@@ -38,25 +30,44 @@ try:
|
||||
from ring_attention_pytorch.ring_flash_attention_cuda import ring_flash_attn_cuda
|
||||
except:
|
||||
RING_ATTENTION_IS_AVAILABLE = False
|
||||
|
||||
|
||||
|
||||
# from timm.models.layers.helpers import to_2tuple
|
||||
# from timm.models.layers.trace_utils import _assert
|
||||
|
||||
def modulate(x, shift, scale):
|
||||
return x * (1 + scale.unsqueeze(1)) + shift.unsqueeze(1)
|
||||
|
||||
|
||||
#################################################################################
|
||||
# Attention Layers from TIMM #
|
||||
#################################################################################
|
||||
|
||||
class Attention(nn.Module):
|
||||
def __init__(self, dim, num_heads=8, qkv_bias=False, attn_drop=0., proj_drop=0., use_lora=False, attention_mode='math', eps=1e-12, causal=True, ring_bucket_size=1024):
|
||||
def __init__(self,
|
||||
dim,
|
||||
num_heads=8,
|
||||
qkv_bias=False,
|
||||
attn_drop=0.,
|
||||
proj_drop=0.,
|
||||
use_lora=False,
|
||||
attention_mode='math',
|
||||
eps=1e-12,
|
||||
causal=True,
|
||||
ring_bucket_size=1024,
|
||||
attention_pe_mode=None,
|
||||
hw: Union[int, Tuple[int, int]] = 16, # (h, w)
|
||||
pt_hw: Union[int, Tuple[int, int]] = 16, # (h, w)
|
||||
intp_vfreq: bool = True, # vision position interpolation
|
||||
):
|
||||
super().__init__()
|
||||
assert dim % num_heads == 0, 'dim should be divisible by num_heads'
|
||||
self.num_heads = num_heads
|
||||
head_dim = dim // num_heads
|
||||
self.scale = head_dim ** -0.5
|
||||
self.attention_mode = attention_mode
|
||||
self.attention_pe_mode = attention_pe_mode
|
||||
|
||||
self.qkv = nn.Linear(dim, dim * 3, bias=qkv_bias)
|
||||
self.attn_drop = nn.Dropout(attn_drop)
|
||||
self.proj = nn.Linear(dim, dim)
|
||||
@@ -65,27 +76,52 @@ class Attention(nn.Module):
|
||||
self.causal = causal
|
||||
self.ring_bucket_size = ring_bucket_size
|
||||
|
||||
def forward(self, x, attention_mask):
|
||||
if self.attention_pe_mode == '2d_rope':
|
||||
half_head_dim = dim // num_heads // 2
|
||||
self.hw = to_2tuple(hw)
|
||||
self.rope = VisionRotaryEmbeddingFast(
|
||||
dim=half_head_dim,
|
||||
pt_hw=to_2tuple(pt_hw),
|
||||
ft_hw=self.hw if intp_vfreq else None,
|
||||
)
|
||||
|
||||
def forward(self, x, attn_mask):
|
||||
B, N, C = x.shape
|
||||
qkv = self.qkv(x).reshape(B, N, 3, self.num_heads, C // self.num_heads).permute(2, 0, 3, 1, 4).contiguous()
|
||||
q, k, v = qkv.unbind(0) # make torchscript happy (cannot use tensor as tuple) b h n c
|
||||
|
||||
if self.attention_mode == 'xformers': # cause loss nan while using with amp
|
||||
assert q.ndim == 4 and (attention_mask is None or torch.all(attention_mask.bool()))
|
||||
q, k, v = q.transpose(1, 2), k.transpose(1, 2), v.transpose(1, 2)
|
||||
x = xformers.ops.memory_efficient_attention(q, k, v, p=self.attn_drop.p, scale=self.scale).reshape(B, N, C)
|
||||
q, k, v = qkv.unbind(0) # make torchscript happy (cannot use tensor as tuple) b h n c
|
||||
if attn_mask is not None:
|
||||
attn_mask = attn_mask.repeat(1, self.num_heads, 1, 1).to(q.dtype)
|
||||
|
||||
if self.attention_pe_mode == '2d_rope':
|
||||
q_t = q.view(B, self.num_heads, -1, self.hw[0] * self.hw[1], C // self.num_heads)
|
||||
ro_q_t = self.rope(q_t)
|
||||
q = ro_q_t.view(B, self.num_heads, N, C // self.num_heads)
|
||||
|
||||
k_t = k.view(B, self.num_heads, -1, self.hw[0] * self.hw[1], C // self.num_heads)
|
||||
ro_k_t = self.rope(k_t)
|
||||
k = ro_k_t.view(B, self.num_heads, N, C // self.num_heads)
|
||||
|
||||
if self.attention_mode == 'xformers': # require pytorch 2.0
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False, enable_flash=False, enable_mem_efficient=True):
|
||||
x = F.scaled_dot_product_attention(q, k, v, attn_mask=attn_mask,
|
||||
dropout_p=self.attn_drop.p, scale=self.scale).reshape(B, N, C)
|
||||
|
||||
elif self.attention_mode == 'flash': # require pytorch 2.0
|
||||
# https://github.com/PKU-YuanGroup/Open-Sora-Plan/issues/109
|
||||
if attn_mask is None or torch.all(attn_mask.bool()):
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False, enable_flash=True, enable_mem_efficient=False):
|
||||
x = F.scaled_dot_product_attention(q, k, v,
|
||||
dropout_p=self.attn_drop.p, scale=self.scale).reshape(B, N, C)
|
||||
else: # turn to xformers
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False, enable_flash=False, enable_mem_efficient=True):
|
||||
x = F.scaled_dot_product_attention(q, k, v, attn_mask=attn_mask,
|
||||
dropout_p=self.attn_drop.p, scale=self.scale).reshape(B, N, C)
|
||||
|
||||
elif self.attention_mode == 'flash':
|
||||
assert attention_mask is None or torch.all(attention_mask.bool())
|
||||
# cause loss nan while using with amp
|
||||
# Optionally use the context manager to ensure one of the fused kerenels is run
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False, enable_flash=True, enable_mem_efficient=False):
|
||||
x = torch.nn.functional.scaled_dot_product_attention(q, k, v, dropout_p=self.attn_drop.p, scale=self.scale).reshape(B, N, C) # require pytorch 2.0
|
||||
|
||||
elif self.attention_mode == 'math':
|
||||
attn = (q @ k.transpose(-2, -1)) * self.scale
|
||||
if attention_mask is not None:
|
||||
attn = attn + attention_mask
|
||||
if attn_mask is not None:
|
||||
attn_bias = self.make_attn_bias(attn_mask)
|
||||
attn = attn + attn_bias
|
||||
attn = attn.softmax(dim=-1)
|
||||
if torch.any(torch.isnan(attn)):
|
||||
print('torch.any(torch.isnan(attn))')
|
||||
@@ -106,6 +142,13 @@ class Attention(nn.Module):
|
||||
x = self.proj_drop(x)
|
||||
return x
|
||||
|
||||
def make_attn_bias(self, attn_mask):
|
||||
# The numerical range of bfloat16, float16 can't conver -1e8
|
||||
# Refer to https://discuss.pytorch.org/t/runtimeerror-value-cannot-be-converted-to-type-at-half-without-overflow-1e-30/109768
|
||||
attn_bias = torch.where(attn_mask == 0, -1e8 if attn_mask.dtype == torch.float32 else -1e4, attn_mask)
|
||||
attn_bias = torch.where(attn_mask == 1, 0., attn_bias)
|
||||
return attn_bias
|
||||
|
||||
|
||||
#################################################################################
|
||||
# Embedding Layers for Timesteps and Class Labels #
|
||||
@@ -115,6 +158,7 @@ class TimestepEmbedder(nn.Module):
|
||||
"""
|
||||
Embeds scalar timesteps into vector representations.
|
||||
"""
|
||||
|
||||
def __init__(self, hidden_size, frequency_embedding_size=256):
|
||||
super().__init__()
|
||||
self.mlp = nn.Sequential(
|
||||
@@ -155,6 +199,7 @@ class LabelEmbedder(nn.Module):
|
||||
"""
|
||||
Embeds class labels into vector representations. Also handles label dropout for classifier-free guidance.
|
||||
"""
|
||||
|
||||
def __init__(self, num_classes, hidden_size, dropout_prob):
|
||||
super().__init__()
|
||||
use_cfg_embedding = dropout_prob > 0
|
||||
@@ -189,6 +234,7 @@ class TransformerBlock(nn.Module):
|
||||
"""
|
||||
A Latte tansformer block with adaptive layer norm zero (adaLN-Zero) conditioning.
|
||||
"""
|
||||
|
||||
def __init__(self, hidden_size, num_heads, mlp_ratio=4.0, **block_kwargs):
|
||||
super().__init__()
|
||||
self.norm1 = nn.LayerNorm(hidden_size, elementwise_affine=False, eps=1e-6)
|
||||
@@ -202,9 +248,9 @@ class TransformerBlock(nn.Module):
|
||||
nn.Linear(hidden_size, 6 * hidden_size, bias=True)
|
||||
)
|
||||
|
||||
def forward(self, x, c, attention_mask):
|
||||
def forward(self, x, c, attn_bias):
|
||||
shift_msa, scale_msa, gate_msa, shift_mlp, scale_mlp, gate_mlp = self.adaLN_modulation(c).chunk(6, dim=1)
|
||||
x = x + gate_msa.unsqueeze(1) * self.attn(modulate(self.norm1(x), shift_msa, scale_msa), attention_mask)
|
||||
x = x + gate_msa.unsqueeze(1) * self.attn(modulate(self.norm1(x), shift_msa, scale_msa), attn_bias)
|
||||
x = x + gate_mlp.unsqueeze(1) * self.mlp(modulate(self.norm2(x), shift_mlp, scale_mlp))
|
||||
return x
|
||||
|
||||
@@ -213,6 +259,7 @@ class FinalLayer(nn.Module):
|
||||
"""
|
||||
The final layer of Latte.
|
||||
"""
|
||||
|
||||
def __init__(self, hidden_size, patch_size_t, patch_size, out_channels):
|
||||
super().__init__()
|
||||
self.norm_final = nn.LayerNorm(hidden_size, elementwise_affine=False, eps=1e-6)
|
||||
@@ -233,22 +280,26 @@ class Latte(nn.Module):
|
||||
"""
|
||||
Diffusion model with a Transformer backbone.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
input_size=32,
|
||||
patch_size=2,
|
||||
patch_size_t=1,
|
||||
in_channels=4,
|
||||
hidden_size=1152,
|
||||
depth=28,
|
||||
num_heads=16,
|
||||
mlp_ratio=4.0,
|
||||
num_frames=16,
|
||||
class_dropout_prob=0.1,
|
||||
num_classes=1000,
|
||||
learn_sigma=True,
|
||||
extras=1,
|
||||
attention_mode='math',
|
||||
attention_pe_mode=None,
|
||||
pt_input_size: Union[int, Tuple[int, int]] = None, # (h, w)
|
||||
intp_vfreq: bool = True, # vision position interpolation
|
||||
):
|
||||
super().__init__()
|
||||
self.learn_sigma = learn_sigma
|
||||
@@ -267,11 +318,11 @@ class Latte(nn.Module):
|
||||
|
||||
if self.extras == 2:
|
||||
self.y_embedder = LabelEmbedder(num_classes, hidden_size, class_dropout_prob)
|
||||
if self.extras == 78: # timestep + text_embedding
|
||||
if self.extras == 78: # timestep + text_embedding
|
||||
self.text_embedding_projection = nn.Sequential(
|
||||
nn.SiLU(),
|
||||
nn.Linear(77 * 768, hidden_size, bias=True)
|
||||
)
|
||||
nn.SiLU(),
|
||||
nn.Linear(77 * 768, hidden_size, bias=True)
|
||||
)
|
||||
|
||||
num_patches = self.x_embedder.num_patches
|
||||
# Will use fixed sin-cos embedding:
|
||||
@@ -279,8 +330,13 @@ class Latte(nn.Module):
|
||||
self.temp_embed = nn.Parameter(torch.zeros(1, num_frames, hidden_size), requires_grad=False)
|
||||
self.hidden_size = hidden_size
|
||||
|
||||
if pt_input_size is None:
|
||||
pt_input_size = input_size
|
||||
self.blocks = nn.ModuleList([
|
||||
TransformerBlock(hidden_size, num_heads, mlp_ratio=mlp_ratio, attention_mode=attention_mode) for _ in range(depth)
|
||||
TransformerBlock(hidden_size, num_heads, mlp_ratio=mlp_ratio, attention_mode=attention_mode,
|
||||
attention_pe_mode=attention_pe_mode, hw=input_size, pt_hw=pt_input_size,
|
||||
intp_vfreq=intp_vfreq
|
||||
) for _ in range(depth)
|
||||
])
|
||||
|
||||
self.final_layer = FinalLayer(hidden_size, patch_size_t, patch_size, self.out_channels)
|
||||
@@ -293,6 +349,7 @@ class Latte(nn.Module):
|
||||
torch.nn.init.xavier_uniform_(module.weight)
|
||||
if module.bias is not None:
|
||||
nn.init.constant_(module.bias, 0)
|
||||
|
||||
self.apply(_basic_init)
|
||||
|
||||
# Initialize (and freeze) pos_embed by sin-cos embedding:
|
||||
@@ -345,22 +402,21 @@ class Latte(nn.Module):
|
||||
def ckpt_forward(*inputs):
|
||||
outputs = module(*inputs)
|
||||
return outputs
|
||||
|
||||
return ckpt_forward
|
||||
|
||||
def make_mask(self, attention_mask, dtype):
|
||||
def make_mask(self, attention_mask):
|
||||
attention_mask = attention_mask.flatten(1).unsqueeze(-1) # bs t h w -> bs thw 1
|
||||
attention_mask = attention_mask @ attention_mask.transpose(1, 2) # bs thw 1 @ bs 1 thw = bs thw thw
|
||||
attention_mask = attention_mask.unsqueeze(1)
|
||||
attention_mask = attention_mask.masked_fill(attention_mask == 0, 1e-8)
|
||||
# attention_mask = attention_mask.masked_fill(attention_mask == 0, torch.finfo(dtype).min)
|
||||
return attention_mask
|
||||
|
||||
# @torch.cuda.amp.autocast()
|
||||
# @torch.compile
|
||||
def forward(self,
|
||||
x,
|
||||
t,
|
||||
y=None,
|
||||
def forward(self,
|
||||
x,
|
||||
t,
|
||||
y=None,
|
||||
text_embedding=None,
|
||||
attention_mask=None):
|
||||
"""
|
||||
@@ -373,10 +429,10 @@ class Latte(nn.Module):
|
||||
attention_mask_temproal, attention_mask_spatial = None, None
|
||||
if attention_mask is not None:
|
||||
attention_mask_spatial = rearrange(attention_mask, 'b t h w -> (b t) h w')
|
||||
attention_mask_spatial = self.make_mask(attention_mask_spatial, x.dtype)
|
||||
attention_mask_spatial = self.make_mask(attention_mask_spatial)
|
||||
|
||||
attention_mask_temproal = rearrange(attention_mask, 'b t h w -> (b h w) t')
|
||||
attention_mask_temproal = self.make_mask(attention_mask_temproal, x.dtype)
|
||||
attention_mask_temproal = self.make_mask(attention_mask_temproal)
|
||||
|
||||
batches, frames, channels, high, weight = x.shape
|
||||
|
||||
@@ -385,7 +441,6 @@ class Latte(nn.Module):
|
||||
x = self.x_embedder(x) + self.pos_embed
|
||||
t = self.t_embedder(t)
|
||||
|
||||
|
||||
timestep_spatial = repeat(t, 'n d -> (n c) d', c=self.temp_embed.shape[1])
|
||||
timestep_temp = repeat(t, 'n d -> (n c) d', c=self.pos_embed.shape[1])
|
||||
|
||||
@@ -399,7 +454,7 @@ class Latte(nn.Module):
|
||||
text_embedding_temp = repeat(text_embedding, 'n d -> (n c) d', c=self.pos_embed.shape[1])
|
||||
|
||||
for i in range(0, len(self.blocks), 2):
|
||||
spatial_block, temp_block = self.blocks[i:i+2]
|
||||
spatial_block, temp_block = self.blocks[i:i + 2]
|
||||
if self.extras == 2:
|
||||
c = timestep_spatial + y_spatial
|
||||
elif self.extras == 78:
|
||||
@@ -433,8 +488,8 @@ class Latte(nn.Module):
|
||||
c = timestep_spatial + y_spatial
|
||||
else:
|
||||
c = timestep_spatial
|
||||
x = self.final_layer(x, c)
|
||||
x = self.unpatchify(x)
|
||||
x = self.final_layer(x, c)
|
||||
x = self.unpatchify(x)
|
||||
x = rearrange(x, '(b f) c h w -> b f c h w', b=batches)
|
||||
return x
|
||||
|
||||
@@ -454,7 +509,7 @@ class Latte(nn.Module):
|
||||
# eps, rest = model_out[:, :, :4, ...], model_out[:, :, 4:, ...]
|
||||
cond_eps, uncond_eps = torch.split(eps, len(eps) // 2, dim=0)
|
||||
half_eps = uncond_eps + cfg_scale * (cond_eps - uncond_eps)
|
||||
eps = torch.cat([half_eps, half_eps], dim=0)
|
||||
eps = torch.cat([half_eps, half_eps], dim=0)
|
||||
return torch.cat([eps, rest], dim=2)
|
||||
|
||||
|
||||
@@ -467,6 +522,7 @@ def get_1d_sincos_temp_embed(embed_dim, length):
|
||||
pos = torch.arange(0, length).unsqueeze(1)
|
||||
return get_1d_sincos_pos_embed_from_grid(embed_dim, pos)
|
||||
|
||||
|
||||
def get_2d_sincos_pos_embed(embed_dim, grid_size, cls_token=False, extra_tokens=0):
|
||||
"""
|
||||
grid_size: int of the grid height and width
|
||||
@@ -489,8 +545,8 @@ def get_2d_sincos_pos_embed_from_grid(embed_dim, grid):
|
||||
assert embed_dim % 2 == 0
|
||||
|
||||
# use half of dimensions to encode grid_h
|
||||
emb_h = get_1d_sincos_pos_embed_from_grid(embed_dim // 2, grid[0])
|
||||
emb_w = get_1d_sincos_pos_embed_from_grid(embed_dim // 2, grid[1])
|
||||
emb_h = get_1d_sincos_pos_embed_from_grid(embed_dim // 2, grid[0])
|
||||
emb_w = get_1d_sincos_pos_embed_from_grid(embed_dim // 2, grid[1])
|
||||
|
||||
emb = np.concatenate([emb_h, emb_w], axis=1)
|
||||
return emb
|
||||
@@ -505,15 +561,15 @@ def get_1d_sincos_pos_embed_from_grid(embed_dim, pos):
|
||||
assert embed_dim % 2 == 0
|
||||
omega = np.arange(embed_dim // 2, dtype=np.float64)
|
||||
omega /= embed_dim / 2.
|
||||
omega = 1. / 10000**omega
|
||||
omega = 1. / 10000 ** omega
|
||||
|
||||
pos = pos.reshape(-1)
|
||||
out = np.einsum('m,d->md', pos, omega)
|
||||
pos = pos.reshape(-1)
|
||||
out = np.einsum('m,d->md', pos, omega)
|
||||
|
||||
emb_sin = np.sin(out)
|
||||
emb_cos = np.cos(out)
|
||||
emb_sin = np.sin(out)
|
||||
emb_cos = np.cos(out)
|
||||
|
||||
emb = np.concatenate([emb_sin, emb_cos], axis=1)
|
||||
emb = np.concatenate([emb_sin, emb_cos], axis=1)
|
||||
return emb
|
||||
|
||||
|
||||
@@ -524,49 +580,59 @@ def get_1d_sincos_pos_embed_from_grid(embed_dim, pos):
|
||||
def Latte_XL_122(**kwargs):
|
||||
return Latte(depth=28, hidden_size=1152, patch_size_t=1, patch_size=2, num_heads=16, **kwargs)
|
||||
|
||||
|
||||
def Latte_XL_144(**kwargs):
|
||||
return Latte(depth=28, hidden_size=1152, patch_size_t=1, patch_size=4, num_heads=16, **kwargs)
|
||||
|
||||
|
||||
def Latte_XL_188(**kwargs):
|
||||
return Latte(depth=28, hidden_size=1152, patch_size_t=1, patch_size=8, num_heads=16, **kwargs)
|
||||
|
||||
|
||||
def Latte_L_122(**kwargs):
|
||||
return Latte(depth=24, hidden_size=1024, patch_size_t=1, patch_size=2, num_heads=16, **kwargs)
|
||||
|
||||
|
||||
def Latte_L_144(**kwargs):
|
||||
return Latte(depth=24, hidden_size=1024, patch_size_t=1, patch_size=4, num_heads=16, **kwargs)
|
||||
|
||||
|
||||
def Latte_L_188(**kwargs):
|
||||
return Latte(depth=24, hidden_size=1024, patch_size_t=1, patch_size=8, num_heads=16, **kwargs)
|
||||
|
||||
|
||||
def Latte_B_122(**kwargs):
|
||||
return Latte(depth=12, hidden_size=768, patch_size=2, num_heads=12, **kwargs)
|
||||
|
||||
|
||||
def Latte_B_144(**kwargs):
|
||||
return Latte(depth=12, hidden_size=768, patch_size_t=1, patch_size=4, num_heads=12, **kwargs)
|
||||
|
||||
|
||||
def Latte_B_188(**kwargs):
|
||||
return Latte(depth=12, hidden_size=768, patch_size_t=1, patch_size=8, num_heads=12, **kwargs)
|
||||
|
||||
|
||||
def Latte_S_122(**kwargs):
|
||||
return Latte(depth=12, hidden_size=384, patch_size_t=1, patch_size=2, num_heads=6, **kwargs)
|
||||
|
||||
|
||||
def Latte_S_144(**kwargs):
|
||||
return Latte(depth=12, hidden_size=384, patch_size_t=1, patch_size=4, num_heads=6, **kwargs)
|
||||
|
||||
|
||||
def Latte_S_188(**kwargs):
|
||||
return Latte(depth=12, hidden_size=384, patch_size_t=1, patch_size=8, num_heads=6, **kwargs)
|
||||
|
||||
|
||||
Latte_models = {
|
||||
'Latte-XL/122': Latte_XL_122, 'Latte-XL/144': Latte_XL_144, 'Latte-XL/188': Latte_XL_188,
|
||||
'Latte-L/122': Latte_L_122, 'Latte-L/144': Latte_L_144, 'Latte-L/188': Latte_L_188,
|
||||
'Latte-B/122': Latte_B_122, 'Latte-B/144': Latte_B_144, 'Latte-B/188': Latte_B_188,
|
||||
'Latte-S/122': Latte_S_122, 'Latte-S/144': Latte_S_144, 'Latte-S/188': Latte_S_188,
|
||||
}
|
||||
|
||||
if __name__ == '__main__':
|
||||
|
||||
import torch
|
||||
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
@@ -575,12 +641,13 @@ if __name__ == '__main__':
|
||||
t = torch.tensor([1, 2, 3]).to(device)
|
||||
y = torch.tensor([1, 2, 3]).to(device)
|
||||
network = Latte_XL_122().to(device)
|
||||
from thop import profile
|
||||
from thop import profile
|
||||
|
||||
flops, params = profile(network, inputs=(img, t))
|
||||
print('FLOPs = ' + str(flops/1000**3) + 'G')
|
||||
print('Params = ' + str(params/1000**2) + 'M')
|
||||
print('FLOPs = ' + str(flops / 1000 ** 3) + 'G')
|
||||
print('Params = ' + str(params / 1000 ** 2) + 'M')
|
||||
# y_embeder = LabelEmbedder(num_classes=101, hidden_size=768, dropout_prob=0.5).to(device)
|
||||
# lora.mark_only_lora_as_trainable(network)
|
||||
# out = y_embeder(y, True)
|
||||
# out = network(img, t, y)
|
||||
# print(out.shape)
|
||||
# print(out.shape)
|
||||
@@ -0,0 +1,647 @@
|
||||
# All rights reserved.
|
||||
|
||||
# This source code is licensed under the license found in the
|
||||
# LICENSE file in the root directory of this source tree.
|
||||
# --------------------------------------------------------
|
||||
# References:
|
||||
# GLIDE: https://github.com/openai/glide-text2im
|
||||
# MAE: https://github.com/facebookresearch/mae/blob/main/models_mae.py
|
||||
# --------------------------------------------------------
|
||||
import math
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.utils.checkpoint as cp
|
||||
import numpy as np
|
||||
from torch.nn import functional as F
|
||||
from einops import rearrange, repeat
|
||||
from typing import Tuple, Union
|
||||
from timm.layers import to_2tuple
|
||||
from timm.models.vision_transformer import Mlp, PatchEmbed
|
||||
|
||||
from .VisionRoPE import VisionRotaryEmbeddingFast
|
||||
|
||||
try:
|
||||
# needs to have https://github.com/corl-team/rebased/ installed
|
||||
from fla.ops.triton.rebased_fast import parallel_rebased
|
||||
except:
|
||||
REBASED_IS_AVAILABLE = False
|
||||
|
||||
try:
|
||||
# needs to have https://github.com/lucidrains/ring-attention-pytorch installed
|
||||
from ring_attention_pytorch.ring_flash_attention_cuda import ring_flash_attn_cuda
|
||||
except:
|
||||
RING_ATTENTION_IS_AVAILABLE = False
|
||||
|
||||
from .configuration_latte import LatteConfiguration
|
||||
|
||||
# from timm.models.layers.helpers import to_2tuple
|
||||
# from timm.models.layers.trace_utils import _assert
|
||||
|
||||
def modulate(x, shift, scale):
|
||||
return x * (1 + scale.unsqueeze(1)) + shift.unsqueeze(1)
|
||||
|
||||
#################################################################################
|
||||
# Attention Layers from TIMM #
|
||||
#################################################################################
|
||||
|
||||
class Attention(nn.Module):
|
||||
def __init__(self,
|
||||
dim,
|
||||
num_heads=8,
|
||||
qkv_bias=False,
|
||||
attn_drop=0.,
|
||||
proj_drop=0.,
|
||||
use_lora=False,
|
||||
attention_mode='math',
|
||||
eps=1e-12,
|
||||
causal=True,
|
||||
ring_bucket_size=1024,
|
||||
attention_pe_mode=None,
|
||||
hw: Union[int, Tuple[int, int]] = 16, # (h, w)
|
||||
pt_hw: Union[int, Tuple[int, int]] = 16, # (h, w)
|
||||
intp_vfreq: bool = True, # vision position interpolation
|
||||
):
|
||||
super().__init__()
|
||||
assert dim % num_heads == 0, 'dim should be divisible by num_heads'
|
||||
self.num_heads = num_heads
|
||||
head_dim = dim // num_heads
|
||||
self.scale = head_dim ** -0.5
|
||||
self.attention_mode = attention_mode
|
||||
self.attention_pe_mode = attention_pe_mode
|
||||
|
||||
self.qkv = nn.Linear(dim, dim * 3, bias=qkv_bias)
|
||||
self.attn_drop = nn.Dropout(attn_drop)
|
||||
self.proj = nn.Linear(dim, dim)
|
||||
self.proj_drop = nn.Dropout(proj_drop)
|
||||
self.eps = eps
|
||||
self.causal = causal
|
||||
self.ring_bucket_size = ring_bucket_size
|
||||
|
||||
if self.attention_pe_mode == '2d_rope':
|
||||
half_head_dim = dim // num_heads // 2
|
||||
self.hw = to_2tuple(hw)
|
||||
self.rope = VisionRotaryEmbeddingFast(
|
||||
dim=half_head_dim,
|
||||
pt_hw=to_2tuple(pt_hw),
|
||||
ft_hw=self.hw if intp_vfreq else None,
|
||||
)
|
||||
|
||||
def forward(self, x, attn_mask):
|
||||
B, N, C = x.shape
|
||||
qkv = self.qkv(x).reshape(B, N, 3, self.num_heads, C // self.num_heads).permute(2, 0, 3, 1, 4).contiguous()
|
||||
q, k, v = qkv.unbind(0) # make torchscript happy (cannot use tensor as tuple) b h n c
|
||||
if attn_mask is not None:
|
||||
attn_mask = attn_mask.repeat(1, self.num_heads, 1, 1).to(q.dtype)
|
||||
|
||||
if self.attention_pe_mode == '2d_rope':
|
||||
q_t = q.view(B, self.num_heads, -1, self.hw[0] * self.hw[1], C // self.num_heads)
|
||||
ro_q_t = self.rope(q_t)
|
||||
q = ro_q_t.view(B, self.num_heads, N, C // self.num_heads)
|
||||
|
||||
k_t = k.view(B, self.num_heads, -1, self.hw[0] * self.hw[1], C // self.num_heads)
|
||||
ro_k_t = self.rope(k_t)
|
||||
k = ro_k_t.view(B, self.num_heads, N, C // self.num_heads)
|
||||
|
||||
if self.attention_mode == 'xformers': # require pytorch 2.0
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False, enable_flash=False, enable_mem_efficient=True):
|
||||
x = F.scaled_dot_product_attention(q, k, v, attn_mask=attn_mask,
|
||||
dropout_p=self.attn_drop.p, scale=self.scale).reshape(B, N, C)
|
||||
|
||||
elif self.attention_mode == 'flash': # require pytorch 2.0
|
||||
# https://github.com/PKU-YuanGroup/Open-Sora-Plan/issues/109
|
||||
if attn_mask is None or torch.all(attn_mask.bool()):
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False, enable_flash=True, enable_mem_efficient=False):
|
||||
x = F.scaled_dot_product_attention(q, k, v,
|
||||
dropout_p=self.attn_drop.p, scale=self.scale).reshape(B, N, C)
|
||||
else: # turn to xformers
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False, enable_flash=False, enable_mem_efficient=True):
|
||||
x = F.scaled_dot_product_attention(q, k, v, attn_mask=attn_mask,
|
||||
dropout_p=self.attn_drop.p, scale=self.scale).reshape(B, N, C)
|
||||
|
||||
elif self.attention_mode == 'math':
|
||||
attn = (q @ k.transpose(-2, -1)) * self.scale
|
||||
if attn_mask is not None:
|
||||
attn_bias = self.make_attn_bias(attn_mask)
|
||||
attn = attn + attn_bias
|
||||
attn = attn.softmax(dim=-1)
|
||||
if torch.any(torch.isnan(attn)):
|
||||
print('torch.any(torch.isnan(attn))')
|
||||
attn = attn.masked_fill(torch.isnan(attn), float(0.))
|
||||
attn = self.attn_drop(attn)
|
||||
x = (attn @ v).transpose(1, 2).reshape(B, N, C)
|
||||
|
||||
elif self.attention_mode == 'rebased':
|
||||
x = parallel_rebased(q, k, v, self.eps, True, True).reshape(B, N, C)
|
||||
|
||||
elif self.attention_mode == 'ring':
|
||||
x = ring_flash_attn_cuda(q, k, v, causal=self.causal, bucket_size=self.ring_bucket_size).reshape(B, N, C)
|
||||
|
||||
else:
|
||||
raise NotImplemented
|
||||
|
||||
x = self.proj(x)
|
||||
x = self.proj_drop(x)
|
||||
return x
|
||||
|
||||
def make_attn_bias(self, attn_mask):
|
||||
# The numerical range of bfloat16, float16 can't conver -1e8
|
||||
# Refer to https://discuss.pytorch.org/t/runtimeerror-value-cannot-be-converted-to-type-at-half-without-overflow-1e-30/109768
|
||||
attn_bias = torch.where(attn_mask == 0, -1e8 if attn_mask.dtype == torch.float32 else -1e4, attn_mask)
|
||||
attn_bias = torch.where(attn_mask == 1, 0., attn_bias)
|
||||
return attn_bias
|
||||
|
||||
#################################################################################
|
||||
# Embedding Layers for Timesteps and Class Labels #
|
||||
#################################################################################
|
||||
|
||||
class TimestepEmbedder(nn.Module):
|
||||
"""
|
||||
Embeds scalar timesteps into vector representations.
|
||||
"""
|
||||
def __init__(self, hidden_size, frequency_embedding_size=256):
|
||||
super().__init__()
|
||||
self.mlp = nn.Sequential(
|
||||
nn.Linear(frequency_embedding_size, hidden_size, bias=True),
|
||||
nn.SiLU(),
|
||||
nn.Linear(hidden_size, hidden_size, bias=True),
|
||||
)
|
||||
self.frequency_embedding_size = frequency_embedding_size
|
||||
|
||||
@staticmethod
|
||||
def timestep_embedding(t, dim, max_period=10000):
|
||||
"""
|
||||
Create sinusoidal timestep embeddings.
|
||||
:param t: a 1-D Tensor of N indices, one per batch element.
|
||||
These may be fractional.
|
||||
:param dim: the dimension of the output.
|
||||
:param max_period: controls the minimum frequency of the embeddings.
|
||||
:return: an (N, D) Tensor of positional embeddings.
|
||||
"""
|
||||
# https://github.com/openai/glide-text2im/blob/main/glide_text2im/nn.py
|
||||
half = dim // 2
|
||||
freqs = torch.exp(
|
||||
-math.log(max_period) * torch.arange(start=0, end=half, dtype=torch.float32) / half
|
||||
).to(device=t.device)
|
||||
args = t[:, None].float() * freqs[None]
|
||||
embedding = torch.cat([torch.cos(args), torch.sin(args)], dim=-1)
|
||||
if dim % 2:
|
||||
embedding = torch.cat([embedding, torch.zeros_like(embedding[:, :1])], dim=-1)
|
||||
return embedding
|
||||
|
||||
def forward(self, t):
|
||||
t_freq = self.timestep_embedding(t, self.frequency_embedding_size)
|
||||
t_emb = self.mlp(t_freq)
|
||||
return t_emb
|
||||
|
||||
|
||||
class LabelEmbedder(nn.Module):
|
||||
"""
|
||||
Embeds class labels into vector representations. Also handles label dropout for classifier-free guidance.
|
||||
"""
|
||||
def __init__(self, num_classes, hidden_size, dropout_prob):
|
||||
super().__init__()
|
||||
use_cfg_embedding = dropout_prob > 0
|
||||
self.embedding_table = nn.Embedding(num_classes + use_cfg_embedding, hidden_size)
|
||||
self.num_classes = num_classes
|
||||
self.dropout_prob = dropout_prob
|
||||
|
||||
def token_drop(self, labels, force_drop_ids=None):
|
||||
"""
|
||||
Drops labels to enable classifier-free guidance.
|
||||
"""
|
||||
if force_drop_ids is None:
|
||||
drop_ids = torch.rand(labels.shape[0], device=labels.device) < self.dropout_prob
|
||||
else:
|
||||
drop_ids = force_drop_ids == 1
|
||||
labels = torch.where(drop_ids, self.num_classes, labels)
|
||||
return labels
|
||||
|
||||
def forward(self, labels, train, force_drop_ids=None):
|
||||
use_dropout = self.dropout_prob > 0
|
||||
if (train and use_dropout) or (force_drop_ids is not None):
|
||||
labels = self.token_drop(labels, force_drop_ids)
|
||||
embeddings = self.embedding_table(labels)
|
||||
return embeddings
|
||||
|
||||
|
||||
#################################################################################
|
||||
# Core Latte Model #
|
||||
#################################################################################
|
||||
|
||||
class TransformerBlock(nn.Module):
|
||||
"""
|
||||
A Latte tansformer block with adaptive layer norm zero (adaLN-Zero) conditioning.
|
||||
"""
|
||||
def __init__(self, hidden_size, num_heads, mlp_ratio=4.0, **block_kwargs):
|
||||
super().__init__()
|
||||
self.norm1 = nn.LayerNorm(hidden_size, elementwise_affine=False, eps=1e-6)
|
||||
self.attn = Attention(hidden_size, num_heads=num_heads, qkv_bias=True, **block_kwargs)
|
||||
self.norm2 = nn.LayerNorm(hidden_size, elementwise_affine=False, eps=1e-6)
|
||||
mlp_hidden_dim = int(hidden_size * mlp_ratio)
|
||||
approx_gelu = lambda: nn.GELU(approximate="tanh")
|
||||
self.mlp = Mlp(in_features=hidden_size, hidden_features=mlp_hidden_dim, act_layer=approx_gelu, drop=0)
|
||||
self.adaLN_modulation = nn.Sequential(
|
||||
nn.SiLU(),
|
||||
nn.Linear(hidden_size, 6 * hidden_size, bias=True)
|
||||
)
|
||||
|
||||
def forward(self, x, c, attn_bias):
|
||||
shift_msa, scale_msa, gate_msa, shift_mlp, scale_mlp, gate_mlp = self.adaLN_modulation(c).chunk(6, dim=1)
|
||||
x = x + gate_msa.unsqueeze(1) * self.attn(modulate(self.norm1(x), shift_msa, scale_msa), attn_bias)
|
||||
x = x + gate_mlp.unsqueeze(1) * self.mlp(modulate(self.norm2(x), shift_mlp, scale_mlp))
|
||||
return x
|
||||
|
||||
|
||||
class FinalLayer(nn.Module):
|
||||
"""
|
||||
The final layer of Latte.
|
||||
"""
|
||||
def __init__(self, hidden_size, patch_size_t, patch_size, out_channels):
|
||||
super().__init__()
|
||||
self.norm_final = nn.LayerNorm(hidden_size, elementwise_affine=False, eps=1e-6)
|
||||
self.linear = nn.Linear(hidden_size, patch_size_t * patch_size * patch_size * out_channels, bias=True)
|
||||
self.adaLN_modulation = nn.Sequential(
|
||||
nn.SiLU(),
|
||||
nn.Linear(hidden_size, 2 * hidden_size, bias=True)
|
||||
)
|
||||
|
||||
def forward(self, x, c):
|
||||
shift, scale = self.adaLN_modulation(c).chunk(2, dim=1)
|
||||
x = modulate(self.norm_final(x), shift, scale)
|
||||
x = self.linear(x)
|
||||
return x
|
||||
|
||||
|
||||
class Latte(nn.Module):
|
||||
"""
|
||||
Diffusion model with a Transformer backbone.
|
||||
"""
|
||||
def __init__(self, config: LatteConfiguration):
|
||||
super().__init__()
|
||||
|
||||
input_size = config.input_size
|
||||
patch_size = config.patch_size
|
||||
patch_size_t = config.patch_size_t
|
||||
in_channels = config.in_channels
|
||||
hidden_size = config.hidden_size
|
||||
depth = config.depth
|
||||
num_heads = config.num_heads
|
||||
mlp_ratio = config.mlp_ratio
|
||||
num_frames = config.num_frames
|
||||
class_dropout_prob = config.class_dropout_prob
|
||||
num_classes = config.num_classes
|
||||
learn_sigma = config.learn_sigma
|
||||
extras = config.learn_sigma
|
||||
attention_mode = config.attention_mode
|
||||
attention_pe_mode = config.attention_pe_mode
|
||||
pt_input_size = config.pt_input_size
|
||||
intp_vfreq = config.intp_vfreq
|
||||
|
||||
self.config = config
|
||||
|
||||
self.learn_sigma = learn_sigma
|
||||
self.in_channels = in_channels
|
||||
self.out_channels = in_channels * 2 if learn_sigma else in_channels
|
||||
self.patch_size = patch_size
|
||||
self.patch_size_t = patch_size_t
|
||||
self.num_heads = num_heads
|
||||
self.extras = extras
|
||||
self.num_frames = num_frames
|
||||
self.hidden_size = hidden_size
|
||||
self.gradient_checkpointing = False
|
||||
|
||||
self.x_embedder = PatchEmbed(input_size, patch_size, in_channels, hidden_size, bias=True)
|
||||
self.t_embedder = TimestepEmbedder(hidden_size)
|
||||
|
||||
if self.extras == 2:
|
||||
self.y_embedder = LabelEmbedder(num_classes, hidden_size, class_dropout_prob)
|
||||
if self.extras == 78: # timestep + text_embedding
|
||||
self.text_embedding_projection = nn.Sequential(
|
||||
nn.SiLU(),
|
||||
nn.Linear(77 * 768, hidden_size, bias=True)
|
||||
)
|
||||
|
||||
num_patches = self.x_embedder.num_patches
|
||||
# Will use fixed sin-cos embedding:
|
||||
self.pos_embed = nn.Parameter(torch.zeros(1, num_patches, hidden_size), requires_grad=False)
|
||||
self.temp_embed = nn.Parameter(torch.zeros(1, num_frames, hidden_size), requires_grad=False)
|
||||
self.hidden_size = hidden_size
|
||||
|
||||
if pt_input_size is None:
|
||||
pt_input_size = input_size
|
||||
self.blocks = nn.ModuleList([
|
||||
TransformerBlock(hidden_size, num_heads, mlp_ratio=mlp_ratio, attention_mode=attention_mode,
|
||||
attention_pe_mode=attention_pe_mode, hw=input_size, pt_hw=pt_input_size,
|
||||
intp_vfreq=intp_vfreq
|
||||
) for _ in range(depth)
|
||||
])
|
||||
|
||||
self.final_layer = FinalLayer(hidden_size, patch_size_t, patch_size, self.out_channels)
|
||||
self.initialize_weights()
|
||||
|
||||
def initialize_weights(self):
|
||||
# Initialize transformer layers:
|
||||
def _basic_init(module):
|
||||
if isinstance(module, nn.Linear):
|
||||
torch.nn.init.xavier_uniform_(module.weight)
|
||||
if module.bias is not None:
|
||||
nn.init.constant_(module.bias, 0)
|
||||
self.apply(_basic_init)
|
||||
|
||||
# Initialize (and freeze) pos_embed by sin-cos embedding:
|
||||
pos_embed = get_2d_sincos_pos_embed(self.pos_embed.shape[-1], int(self.x_embedder.num_patches ** 0.5))
|
||||
self.pos_embed.data.copy_(torch.from_numpy(pos_embed).float().unsqueeze(0))
|
||||
|
||||
temp_embed = get_1d_sincos_temp_embed(self.temp_embed.shape[-1], self.temp_embed.shape[-2])
|
||||
self.temp_embed.data.copy_(torch.from_numpy(temp_embed).float().unsqueeze(0))
|
||||
|
||||
# Initialize patch_embed like nn.Linear (instead of nn.Conv2d):
|
||||
w = self.x_embedder.proj.weight.data
|
||||
nn.init.xavier_uniform_(w.view([w.shape[0], -1]))
|
||||
nn.init.constant_(self.x_embedder.proj.bias, 0)
|
||||
|
||||
if self.extras == 2:
|
||||
# Initialize label embedding table:
|
||||
nn.init.normal_(self.y_embedder.embedding_table.weight, std=0.02)
|
||||
|
||||
# Initialize timestep embedding MLP:
|
||||
nn.init.normal_(self.t_embedder.mlp[0].weight, std=0.02)
|
||||
nn.init.normal_(self.t_embedder.mlp[2].weight, std=0.02)
|
||||
|
||||
# Zero-out adaLN modulation layers in Latte blocks:
|
||||
for block in self.blocks:
|
||||
nn.init.constant_(block.adaLN_modulation[-1].weight, 0)
|
||||
nn.init.constant_(block.adaLN_modulation[-1].bias, 0)
|
||||
|
||||
# Zero-out output layers:
|
||||
nn.init.constant_(self.final_layer.adaLN_modulation[-1].weight, 0)
|
||||
nn.init.constant_(self.final_layer.adaLN_modulation[-1].bias, 0)
|
||||
nn.init.constant_(self.final_layer.linear.weight, 0)
|
||||
nn.init.constant_(self.final_layer.linear.bias, 0)
|
||||
|
||||
def unpatchify(self, x):
|
||||
"""
|
||||
x: (N, T, patch_size**2 * C)
|
||||
imgs: (N, H, W, C)
|
||||
"""
|
||||
c = self.out_channels
|
||||
p = self.x_embedder.patch_size[0]
|
||||
h = w = int(x.shape[1] ** 0.5)
|
||||
assert h * w == x.shape[1]
|
||||
|
||||
x = x.reshape(shape=(x.shape[0], h, w, p, p, c))
|
||||
x = torch.einsum('nhwpqc->nchpwq', x)
|
||||
imgs = x.reshape(shape=(x.shape[0], c, h * p, h * p))
|
||||
return imgs
|
||||
|
||||
def ckpt_wrapper(self, module):
|
||||
def ckpt_forward(*inputs):
|
||||
outputs = module(*inputs)
|
||||
return outputs
|
||||
return ckpt_forward
|
||||
|
||||
def make_mask(self, attention_mask):
|
||||
attention_mask = attention_mask.flatten(1).unsqueeze(-1) # bs t h w -> bs thw 1
|
||||
attention_mask = attention_mask @ attention_mask.transpose(1, 2) # bs thw 1 @ bs 1 thw = bs thw thw
|
||||
attention_mask = attention_mask.unsqueeze(1)
|
||||
return attention_mask
|
||||
|
||||
# @torch.cuda.amp.autocast()
|
||||
# @torch.compile
|
||||
def forward(self,
|
||||
x,
|
||||
t,
|
||||
y=None,
|
||||
text_embedding=None,
|
||||
attention_mask=None):
|
||||
"""
|
||||
Forward pass of Latte.
|
||||
x: (N, F, C, H, W) tensor of video inputs
|
||||
t: (N,) tensor of diffusion timesteps
|
||||
y: (N,) tensor of class labels
|
||||
attention_mask: (N, F, H, W)
|
||||
"""
|
||||
attention_mask_temproal, attention_mask_spatial = None, None
|
||||
if attention_mask is not None:
|
||||
attention_mask_spatial = rearrange(attention_mask, 'b t h w -> (b t) h w')
|
||||
attention_mask_spatial = self.make_mask(attention_mask_spatial)
|
||||
|
||||
attention_mask_temproal = rearrange(attention_mask, 'b t h w -> (b h w) t')
|
||||
attention_mask_temproal = self.make_mask(attention_mask_temproal)
|
||||
|
||||
batches, frames, channels, high, weight = x.shape
|
||||
|
||||
x = rearrange(x, 'b f c h w -> (b f) c h w')
|
||||
|
||||
x = self.x_embedder(x) + self.pos_embed
|
||||
t = self.t_embedder(t)
|
||||
|
||||
|
||||
timestep_spatial = repeat(t, 'n d -> (n c) d', c=self.temp_embed.shape[1])
|
||||
timestep_temp = repeat(t, 'n d -> (n c) d', c=self.pos_embed.shape[1])
|
||||
|
||||
if self.extras == 2:
|
||||
y = self.y_embedder(y, self.training)
|
||||
y_spatial = repeat(y, 'n d -> (n c) d', c=self.temp_embed.shape[1])
|
||||
y_temp = repeat(y, 'n d -> (n c) d', c=self.pos_embed.shape[1])
|
||||
elif self.extras == 78:
|
||||
text_embedding = self.text_embedding_projection(text_embedding.reshape(batches, -1))
|
||||
text_embedding_spatial = repeat(text_embedding, 'n d -> (n c) d', c=self.temp_embed.shape[1])
|
||||
text_embedding_temp = repeat(text_embedding, 'n d -> (n c) d', c=self.pos_embed.shape[1])
|
||||
|
||||
for i in range(0, len(self.blocks), 2):
|
||||
spatial_block, temp_block = self.blocks[i:i+2]
|
||||
if self.extras == 2:
|
||||
c = timestep_spatial + y_spatial
|
||||
elif self.extras == 78:
|
||||
c = timestep_spatial + text_embedding_spatial
|
||||
else:
|
||||
c = timestep_spatial
|
||||
if self.gradient_checkpointing and self.training:
|
||||
x = torch.utils.checkpoint.checkpoint(self.ckpt_wrapper(spatial_block), x, c, attention_mask_spatial)
|
||||
else:
|
||||
x = spatial_block(x, c, attention_mask_spatial)
|
||||
|
||||
x = rearrange(x, '(b f) t d -> (b t) f d', b=batches)
|
||||
# Add Time Embedding
|
||||
if i == 0:
|
||||
x = x + self.temp_embed
|
||||
|
||||
if self.extras == 2:
|
||||
c = timestep_temp + y_temp
|
||||
elif self.extras == 78:
|
||||
c = timestep_temp + text_embedding_temp
|
||||
else:
|
||||
c = timestep_temp
|
||||
|
||||
if self.gradient_checkpointing and self.training:
|
||||
x = torch.utils.checkpoint.checkpoint(self.ckpt_wrapper(temp_block), x, c, attention_mask_temproal)
|
||||
else:
|
||||
x = temp_block(x, c, attention_mask_temproal)
|
||||
x = rearrange(x, '(b t) f d -> (b f) t d', b=batches)
|
||||
|
||||
if self.extras == 2:
|
||||
c = timestep_spatial + y_spatial
|
||||
else:
|
||||
c = timestep_spatial
|
||||
x = self.final_layer(x, c)
|
||||
x = self.unpatchify(x)
|
||||
x = rearrange(x, '(b f) c h w -> b f c h w', b=batches)
|
||||
|
||||
return x
|
||||
|
||||
def forward_with_cfg(self, x, t, y=None, cfg_scale=7.0, text_embedding=None, attention_mask=None):
|
||||
"""
|
||||
Forward pass of Latte, but also batches the unconditional forward pass for classifier-free guidance.
|
||||
"""
|
||||
# https://github.com/openai/glide-text2im/blob/main/notebooks/text2im.ipynb
|
||||
half = x[: len(x) // 2]
|
||||
combined = torch.cat([half, half], dim=0)
|
||||
model_out = self.forward(combined, t, y=y, text_embedding=text_embedding, attention_mask=attention_mask)
|
||||
# For exact reproducibility reasons, we apply classifier-free guidance on only
|
||||
# three channels by default. The standard approach to cfg applies it to all channels.
|
||||
# This can be done by uncommenting the following line and commenting-out the line following that.
|
||||
eps, rest = model_out[:, :self.in_channels], model_out[:, self.in_channels:]
|
||||
# eps, rest = model_out[:, :3], model_out[:, 3:]
|
||||
# eps, rest = model_out[:, :, :4, ...], model_out[:, :, 4:, ...]
|
||||
cond_eps, uncond_eps = torch.split(eps, len(eps) // 2, dim=0)
|
||||
half_eps = uncond_eps + cfg_scale * (cond_eps - uncond_eps)
|
||||
eps = torch.cat([half_eps, half_eps], dim=0)
|
||||
return torch.cat([eps, rest], dim=2)
|
||||
|
||||
|
||||
#################################################################################
|
||||
# Sine/Cosine Positional Embedding Functions #
|
||||
#################################################################################
|
||||
# https://github.com/facebookresearch/mae/blob/main/util/pos_embed.py
|
||||
|
||||
def get_1d_sincos_temp_embed(embed_dim, length):
|
||||
pos = torch.arange(0, length).unsqueeze(1)
|
||||
return get_1d_sincos_pos_embed_from_grid(embed_dim, pos)
|
||||
|
||||
def get_2d_sincos_pos_embed(embed_dim, grid_size, cls_token=False, extra_tokens=0):
|
||||
"""
|
||||
grid_size: int of the grid height and width
|
||||
return:
|
||||
pos_embed: [grid_size*grid_size, embed_dim] or [1+grid_size*grid_size, embed_dim] (w/ or w/o cls_token)
|
||||
"""
|
||||
grid_h = np.arange(grid_size, dtype=np.float32)
|
||||
grid_w = np.arange(grid_size, dtype=np.float32)
|
||||
grid = np.meshgrid(grid_w, grid_h) # here w goes first
|
||||
grid = np.stack(grid, axis=0)
|
||||
|
||||
grid = grid.reshape([2, 1, grid_size, grid_size])
|
||||
pos_embed = get_2d_sincos_pos_embed_from_grid(embed_dim, grid)
|
||||
if cls_token and extra_tokens > 0:
|
||||
pos_embed = np.concatenate([np.zeros([extra_tokens, embed_dim]), pos_embed], axis=0)
|
||||
return pos_embed
|
||||
|
||||
|
||||
def get_2d_sincos_pos_embed_from_grid(embed_dim, grid):
|
||||
assert embed_dim % 2 == 0
|
||||
|
||||
# use half of dimensions to encode grid_h
|
||||
emb_h = get_1d_sincos_pos_embed_from_grid(embed_dim // 2, grid[0])
|
||||
emb_w = get_1d_sincos_pos_embed_from_grid(embed_dim // 2, grid[1])
|
||||
|
||||
emb = np.concatenate([emb_h, emb_w], axis=1)
|
||||
return emb
|
||||
|
||||
|
||||
def get_1d_sincos_pos_embed_from_grid(embed_dim, pos):
|
||||
"""
|
||||
embed_dim: output dimension for each position
|
||||
pos: a list of positions to be encoded: size (M,)
|
||||
out: (M, D)
|
||||
"""
|
||||
assert embed_dim % 2 == 0
|
||||
omega = np.arange(embed_dim // 2, dtype=np.float64)
|
||||
omega /= embed_dim / 2.
|
||||
omega = 1. / 10000**omega
|
||||
|
||||
pos = pos.reshape(-1)
|
||||
out = np.einsum('m,d->md', pos, omega)
|
||||
|
||||
emb_sin = np.sin(out)
|
||||
emb_cos = np.cos(out)
|
||||
|
||||
emb = np.concatenate([emb_sin, emb_cos], axis=1)
|
||||
return emb
|
||||
|
||||
|
||||
#################################################################################
|
||||
# Latte Configs #
|
||||
#################################################################################
|
||||
|
||||
from .configuration_latte import (
|
||||
Latte_XL_122_Config, Latte_XL_144_Config, Latte_XL_188_Config,
|
||||
Latte_L_122_Config, Latte_L_144_Config, Latte_L_188_Config,
|
||||
Latte_B_122_Config, Latte_B_144_Config, Latte_B_188_Config,
|
||||
Latte_S_122_Config, Latte_S_144_Config, Latte_S_188_Config,
|
||||
)
|
||||
|
||||
def Latte_XL_122(**kwargs):
|
||||
return Latte(Latte_XL_122_Config(**kwargs))
|
||||
|
||||
def Latte_XL_144(**kwargs):
|
||||
return Latte(Latte_XL_144_Config(**kwargs))
|
||||
|
||||
def Latte_XL_188(**kwargs):
|
||||
return Latte(Latte_XL_188_Config(**kwargs))
|
||||
|
||||
def Latte_L_122(**kwargs):
|
||||
return Latte(Latte_L_122_Config(**kwargs))
|
||||
|
||||
def Latte_L_144(**kwargs):
|
||||
return Latte(Latte_L_144_Config(**kwargs))
|
||||
|
||||
def Latte_L_188(**kwargs):
|
||||
return Latte(Latte_L_188_Config(**kwargs))
|
||||
|
||||
def Latte_B_122(**kwargs):
|
||||
return Latte(Latte_B_122_Config(**kwargs))
|
||||
|
||||
def Latte_B_144(**kwargs):
|
||||
return Latte(Latte_B_144_Config(**kwargs))
|
||||
|
||||
def Latte_B_188(**kwargs):
|
||||
return Latte(Latte_B_188_Config(**kwargs))
|
||||
|
||||
def Latte_S_122(**kwargs):
|
||||
return Latte(Latte_S_122_Config(**kwargs))
|
||||
|
||||
def Latte_S_144(**kwargs):
|
||||
return Latte(Latte_S_144_Config(**kwargs))
|
||||
|
||||
def Latte_S_188(**kwargs):
|
||||
return Latte(Latte_S_188_Config(**kwargs))
|
||||
|
||||
|
||||
Latte_models = {
|
||||
"Latte-XL/122": Latte_XL_122, "Latte-XL/144": Latte_XL_144, "Latte-XL/188": Latte_XL_188,
|
||||
"Latte-L/122": Latte_L_122, "Latte-L/144": Latte_L_144, "Latte-L/188": Latte_L_188,
|
||||
"Latte-B/122": Latte_B_122, "Latte-B/144": Latte_B_144, "Latte-B/188": Latte_B_188,
|
||||
"Latte-S/122": Latte_S_122, "Latte-S/144": Latte_S_144, "Latte-S/188": Latte_S_188,
|
||||
}
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
|
||||
import torch
|
||||
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
|
||||
img = torch.randn(3, 16, 4, 32, 32).to(device)
|
||||
t = torch.tensor([1, 2, 3]).to(device)
|
||||
y = torch.tensor([1, 2, 3]).to(device)
|
||||
network = Latte_XL_122().to(device)
|
||||
from thop import profile
|
||||
flops, params = profile(network, inputs=(img, t))
|
||||
print('FLOPs = ' + str(flops/1000**3) + 'G')
|
||||
print('Params = ' + str(params/1000**2) + 'M')
|
||||
# y_embeder = LabelEmbedder(num_classes=101, hidden_size=768, dropout_prob=0.5).to(device)
|
||||
# lora.mark_only_lora_as_trainable(network)
|
||||
# out = y_embeder(y, True)
|
||||
# out = network(img, t, y)
|
||||
# print(out.shape)
|
||||
+28
-16
@@ -48,10 +48,8 @@ def main(args):
|
||||
assert torch.cuda.is_available(), "Training currently requires at least one GPU."
|
||||
|
||||
# Setup accelerator:
|
||||
accelerator = Accelerator()
|
||||
accelerator = Accelerator(mixed_precision=args.mixed_precision, gradient_accumulation_steps=args.gradient_accumulation_steps)
|
||||
device = accelerator.device
|
||||
args.mixed_precision = accelerator.mixed_precision
|
||||
args.gradient_accumulation_steps = accelerator.gradient_accumulation_steps
|
||||
|
||||
# Setup an experiment folder:
|
||||
if accelerator.is_main_process:
|
||||
@@ -67,6 +65,7 @@ def main(args):
|
||||
tb_writer = create_tensorboard(experiment_dir)
|
||||
logger.info(f"Experiment directory created at {experiment_dir}")
|
||||
logger.info(f'{args}')
|
||||
logger.info(f'{accelerator}')
|
||||
else:
|
||||
logger = create_logger(None)
|
||||
tb_writer = None
|
||||
@@ -126,8 +125,9 @@ def main(args):
|
||||
|
||||
model = model.to(device)
|
||||
# Note that parameter initialization is done within the DiT constructor
|
||||
ema = deepcopy(model).to(device) # Create an EMA of the model for use after training
|
||||
requires_grad(ema, False)
|
||||
if args.use_ema:
|
||||
ema = deepcopy(model).to(device) # Create an EMA of the model for use after training
|
||||
requires_grad(ema, False)
|
||||
diffusion = create_diffusion(timestep_respacing="") # default: 1000 steps, linear noise schedule
|
||||
|
||||
if args.use_compile:
|
||||
@@ -166,9 +166,10 @@ def main(args):
|
||||
)
|
||||
|
||||
# Prepare models for training:
|
||||
update_ema(ema, model, decay=0) # Ensure EMA is initialized with synced weights
|
||||
if args.use_ema:
|
||||
update_ema(ema, model, decay=0) # Ensure EMA is initialized with synced weights
|
||||
ema.eval() # EMA model should always be in eval mode
|
||||
model.train() # important! This enables embedding dropout for classifier-free guidance
|
||||
ema.eval() # EMA model should always be in eval mode
|
||||
model, opt, loader, lr_scheduler = accelerator.prepare(model, opt, loader, lr_scheduler)
|
||||
|
||||
# Variables for monitoring/logging purposes:
|
||||
@@ -206,6 +207,14 @@ def main(args):
|
||||
|
||||
if accelerator.is_main_process:
|
||||
logger.info(f"Training for {num_train_epochs} epochs...")
|
||||
|
||||
if args.mixed_precision == "bf16":
|
||||
dtype = torch.bfloat16
|
||||
elif args.mixed_precision == "fp16":
|
||||
dtype = torch.float16
|
||||
else:
|
||||
dtype = torch.float32
|
||||
|
||||
for epoch in range(first_epoch, num_train_epochs):
|
||||
logger.info(f"Beginning epoch {epoch}...")
|
||||
for step, (x, y, attn_mask) in enumerate(loader):
|
||||
@@ -218,18 +227,17 @@ def main(args):
|
||||
# Map input images to latent space + normalize latents
|
||||
x = ae.encode(x) # B C T H W -> B T C H W
|
||||
|
||||
|
||||
if args.extras == 78: # text-to-video
|
||||
raise 'T2V training are Not supported at this moment!'
|
||||
elif args.extras == 2:
|
||||
model_kwargs = dict(y=y, attention_mask=attn_mask)
|
||||
else:
|
||||
model_kwargs = dict(y=None, attention_mask=attn_mask)
|
||||
|
||||
t = torch.randint(0, diffusion.num_timesteps, (x.shape[0],), device=device)
|
||||
loss_dict = diffusion.training_losses(model, x, t, model_kwargs)
|
||||
loss = loss_dict["loss"].mean()
|
||||
opt.zero_grad()
|
||||
with torch.autocast(device_type='cuda', dtype=dtype):
|
||||
t = torch.randint(0, diffusion.num_timesteps, (x.shape[0],), device=device)
|
||||
loss_dict = diffusion.training_losses(model, x, t, model_kwargs)
|
||||
loss = loss_dict["loss"].mean()
|
||||
opt.zero_grad()
|
||||
|
||||
accelerator.backward(loss)
|
||||
|
||||
@@ -240,7 +248,8 @@ def main(args):
|
||||
|
||||
opt.step()
|
||||
|
||||
update_ema(ema, model.module)
|
||||
if args.use_ema:
|
||||
update_ema(ema, model.module)
|
||||
|
||||
# Log loss values:
|
||||
running_loss += loss.item()
|
||||
@@ -272,10 +281,11 @@ def main(args):
|
||||
if accelerator.is_main_process:
|
||||
checkpoint = {
|
||||
"model": model.module.state_dict(),
|
||||
"ema": ema.state_dict(),
|
||||
"opt": opt.state_dict(),
|
||||
"args": args
|
||||
}
|
||||
if args.use_ema:
|
||||
checkpoint.update({"ema": ema.state_dict()})
|
||||
checkpoint_path = f"{checkpoint_dir}/{train_steps:07d}.pt"
|
||||
torch.save(checkpoint, checkpoint_path)
|
||||
logger.info(f"Saved checkpoint to {checkpoint_path}")
|
||||
@@ -318,10 +328,12 @@ if __name__ == "__main__":
|
||||
parser.add_argument("--resume-from-checkpoint", action="store_true")
|
||||
parser.add_argument("--gradient-checkpointing", action="store_true")
|
||||
parser.add_argument("--use-compile", action="store_true")
|
||||
parser.add_argument("--use-ema", action="store_true")
|
||||
parser.add_argument("--lr", type=float, default=1e-4)
|
||||
parser.add_argument("--lr-warmup-steps", type=int, default=0)
|
||||
parser.add_argument("--attention_mode", type=str, choices=['xformers', 'math', 'flash'], default="math")
|
||||
|
||||
parser.add_argument("--gradient-accumulation-steps", type=int, default=1)
|
||||
parser.add_argument("--mixed-precision", type=str, default=None, choices=[None, "fp16", "bf16"])
|
||||
parser.add_argument("--clip-grad-norm", default=None, type=float, help="the maximum gradient norm (default None)")
|
||||
# --------------------------------------
|
||||
|
||||
|
||||
+3
-4
@@ -14,7 +14,7 @@ classifiers = [
|
||||
]
|
||||
dependencies = [
|
||||
"torch==2.1.2", "torchvision==0.16.2",
|
||||
"transformers==4.32.0", "albumentations==1.4.0", "av==11.0.0", "decord==0.6.0", "einops==0.3.0", "fastapi==0.110.0",
|
||||
"transformers==4.32.0", "albumentations==1.4.0", "av==11.0.0", "decord==0.6.0", "einops==0.7.0", "fastapi==0.110.0",
|
||||
"accelerate==0.21.0", "gdown==5.1.0", "h5py==3.10.0", "idna==3.6", 'imageio==2.34.0', "matplotlib==3.7.5", "numpy==1.24.4",
|
||||
"omegaconf==2.1.1", "opencv-python==4.9.0.80", "opencv-python-headless==4.9.0.80", "pandas==2.0.3", "pillow==10.2.0",
|
||||
"pydub==0.25.1", "pytorch-lightning==1.4.2", "pytorchvideo==0.1.5", "PyYAML==6.0.1", "regex==2023.12.25",
|
||||
@@ -24,9 +24,8 @@ dependencies = [
|
||||
]
|
||||
|
||||
[project.optional-dependencies]
|
||||
dev = [
|
||||
"mypy==1.8.0"
|
||||
]
|
||||
train = ["deepspeed==0.9.5", "pydantic==1.10.13"]
|
||||
dev = ["mypy==1.8.0"]
|
||||
|
||||
|
||||
[project.urls]
|
||||
|
||||
@@ -0,0 +1,11 @@
|
||||
compute_environment: LOCAL_MACHINE
|
||||
distributed_type: MULTI_GPU
|
||||
fsdp_config: {}
|
||||
machine_rank: 0
|
||||
main_process_ip: null
|
||||
main_process_port: 29501
|
||||
main_training_function: main
|
||||
num_machines: 1
|
||||
num_processes: 8
|
||||
gpu_ids: 0,1,2,3,4,5,6,7
|
||||
use_cpu: false
|
||||
@@ -0,0 +1,13 @@
|
||||
compute_environment: LOCAL_MACHINE
|
||||
distributed_type: DEEPSPEED
|
||||
deepspeed_config:
|
||||
deepspeed_config_file: scripts/accelerate_configs/zero2_offload.json
|
||||
fsdp_config: {}
|
||||
machine_rank: 0
|
||||
main_process_ip: null
|
||||
main_process_port: 29501
|
||||
main_training_function: main
|
||||
num_machines: 1
|
||||
num_processes: 8
|
||||
gpu_ids: 0,1,2,3,4,5,6,7
|
||||
use_cpu: false
|
||||
@@ -2,7 +2,6 @@ compute_environment: LOCAL_MACHINE
|
||||
distributed_type: DEEPSPEED
|
||||
deepspeed_config:
|
||||
deepspeed_config_file: scripts/accelerate_configs/zero3.json
|
||||
zero3_init_flag: true
|
||||
fsdp_config: {}
|
||||
machine_rank: 0
|
||||
main_process_ip: null
|
||||
|
||||
@@ -0,0 +1,13 @@
|
||||
compute_environment: LOCAL_MACHINE
|
||||
distributed_type: DEEPSPEED
|
||||
deepspeed_config:
|
||||
deepspeed_config_file: scripts/accelerate_configs/zero3_offload.json
|
||||
fsdp_config: {}
|
||||
machine_rank: 0
|
||||
main_process_ip: null
|
||||
main_process_port: 29501
|
||||
main_training_function: main
|
||||
num_machines: 1
|
||||
num_processes: 8
|
||||
gpu_ids: 0,1,2,3,4,5,6,7
|
||||
use_cpu: false
|
||||
@@ -0,0 +1,26 @@
|
||||
{
|
||||
"fp16": {
|
||||
"enabled": "auto",
|
||||
"loss_scale": 0,
|
||||
"loss_scale_window": 1000,
|
||||
"initial_scale_power": 16,
|
||||
"hysteresis": 2,
|
||||
"min_loss_scale": 1
|
||||
},
|
||||
"bf16": {
|
||||
"enabled": "auto"
|
||||
},
|
||||
"train_micro_batch_size_per_gpu": "auto",
|
||||
"train_batch_size": "auto",
|
||||
"gradient_accumulation_steps": "auto",
|
||||
"zero_optimization": {
|
||||
"stage": 2,
|
||||
"offload_optimizer": {
|
||||
"device": "cpu"
|
||||
},
|
||||
"overlap_comm": true,
|
||||
"contiguous_gradients": true,
|
||||
"sub_group_size": 1e9,
|
||||
"reduce_bucket_size": "auto"
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,39 @@
|
||||
{
|
||||
"fp16": {
|
||||
"enabled": "auto",
|
||||
"loss_scale": 0,
|
||||
"loss_scale_window": 1000,
|
||||
"initial_scale_power": 16,
|
||||
"hysteresis": 2,
|
||||
"min_loss_scale": 1
|
||||
},
|
||||
"bf16": {
|
||||
"enabled": "auto"
|
||||
},
|
||||
"zero_optimization": {
|
||||
"stage": 3,
|
||||
"offload_optimizer": {
|
||||
"device": "cpu",
|
||||
"pin_memory": true
|
||||
},
|
||||
"offload_param": {
|
||||
"device": "cpu",
|
||||
"pin_memory": true
|
||||
},
|
||||
"overlap_comm": true,
|
||||
"contiguous_gradients": true,
|
||||
"sub_group_size": 1e9,
|
||||
"reduce_bucket_size": "auto",
|
||||
"stage3_prefetch_bucket_size": "auto",
|
||||
"stage3_param_persistence_threshold": "auto",
|
||||
"stage3_max_live_parameters": 1e9,
|
||||
"stage3_max_reuse_distance": 1e9,
|
||||
"gather_16bit_weights_on_model_save": true
|
||||
},
|
||||
"gradient_accumulation_steps": "auto",
|
||||
"gradient_clipping": "auto",
|
||||
"train_batch_size": "auto",
|
||||
"train_micro_batch_size_per_gpu": "auto",
|
||||
"steps_per_print": 1e5,
|
||||
"wall_clock_breakdown": false
|
||||
}
|
||||
@@ -1,9 +0,0 @@
|
||||
|
||||
|
||||
accelerate launch --multi_gpu --num_processes 7 --mixed_precision bf16 opensora/train/train_with_feature.py \
|
||||
--model Latte-XL/122 --dataset landscope_feature \
|
||||
--ae stabilityai/sd-vae-ft-mse \
|
||||
--data-path "/remote-home/yeyang/train_movie/*/*256.npy" --extras 1 \
|
||||
--sample-rate 3 --num-frames 128 --max-image-size 256 \
|
||||
--max-train-steps 1000000 --local-batch-size 5 --lr 1e-4 \
|
||||
--ckpt-every 500 --log-every 50 --gradient-checkpointing
|
||||
@@ -1,9 +0,0 @@
|
||||
|
||||
|
||||
accelerate launch --multi_gpu --num_processes 7 opensora/train/train_with_feature.py \
|
||||
--model Latte-XL/122 --dataset landscope_video_feature \
|
||||
--ae ucf101_stride4x4x4 \
|
||||
--data-path "/remote-home/yeyang/train_movie/*/*s256-videogpt-f16*.npy" --extras 1 \
|
||||
--sample-rate 3 --num-frames 128 --max-image-size 256 \
|
||||
--max-train-steps 1000000 --local-batch-size 16 --lr 1e-4 \
|
||||
--ckpt-every 500 --log-every 50
|
||||
@@ -1,9 +0,0 @@
|
||||
|
||||
|
||||
accelerate launch --multi_gpu --num_processes 8 --mixed_precision bf16 opensora/train/train.py \
|
||||
--model Latte-XL/122 --dataset sky \
|
||||
--ae stabilityai/sd-vae-ft-mse \
|
||||
--data-path "/remote-home/yeyang/sky_timelapse/sky_train/" --extras 1 \
|
||||
--sample-rate 1 --num-frames 128 --max-image-size 256 \
|
||||
--max-train-steps 1000000 --local-batch-size 2 --lr 1e-4 --num-workers 10 \
|
||||
--ckpt-every 500 --log-every 50 --gradient-checkpointing --attention_mode flash
|
||||
@@ -0,0 +1,21 @@
|
||||
|
||||
accelerate launch \
|
||||
--config_file scripts/accelerate_configs/ddp_config.yaml \
|
||||
opensora/train/train.py \
|
||||
--model Latte-XL/122 \
|
||||
--dataset sky \
|
||||
--ae stabilityai/sd-vae-ft-mse \
|
||||
--data-path /remote-home/yeyang/sky_timelapse/sky_train/ \
|
||||
--extras 1 \
|
||||
--sample-rate 3 \
|
||||
--num-frames 16 \
|
||||
--max-image-size 256 \
|
||||
--max-train-steps 1000000 \
|
||||
--local-batch-size 5 \
|
||||
--lr 1e-4 \
|
||||
--ckpt-every 500 \
|
||||
--log-every 50 \
|
||||
--gradient-checkpointing \
|
||||
--attention_mode flash \
|
||||
--mixed-precision bf16 \
|
||||
|
||||
@@ -0,0 +1,20 @@
|
||||
|
||||
accelerate launch \
|
||||
--config_file scripts/accelerate_configs/deepspeed_zero2_config.yaml \
|
||||
opensora/train/train.py \
|
||||
--model Latte-XL/122 \
|
||||
--dataset sky \
|
||||
--ae stabilityai/sd-vae-ft-mse \
|
||||
--data-path /remote-home/yeyang/sky_timelapse/sky_train/ \
|
||||
--extras 1 \
|
||||
--sample-rate 3 \
|
||||
--num-frames 16 \
|
||||
--max-image-size 256 \
|
||||
--max-train-steps 1000000 \
|
||||
--local-batch-size 5 \
|
||||
--lr 1e-4 \
|
||||
--ckpt-every 500 \
|
||||
--log-every 50 \
|
||||
--gradient-checkpointing \
|
||||
--attention_mode flash \
|
||||
--mixed-precision bf16
|
||||
@@ -0,0 +1,20 @@
|
||||
|
||||
accelerate launch \
|
||||
--config_file scripts/accelerate_configs/deepspeed_zero2_offload_config.yaml \
|
||||
opensora/train/train.py \
|
||||
--model Latte-XL/122 \
|
||||
--dataset sky \
|
||||
--ae stabilityai/sd-vae-ft-mse \
|
||||
--data-path /remote-home/yeyang/sky_timelapse/sky_train/ \
|
||||
--extras 1 \
|
||||
--sample-rate 3 \
|
||||
--num-frames 16 \
|
||||
--max-image-size 256 \
|
||||
--max-train-steps 1000000 \
|
||||
--local-batch-size 5 \
|
||||
--lr 1e-4 \
|
||||
--ckpt-every 500 \
|
||||
--log-every 50 \
|
||||
--gradient-checkpointing \
|
||||
--attention_mode flash \
|
||||
--mixed-precision bf16
|
||||
@@ -0,0 +1,20 @@
|
||||
|
||||
accelerate launch \
|
||||
--config_file scripts/accelerate_configs/deepspeed_zero3_config.yaml \
|
||||
opensora/train/train.py \
|
||||
--model Latte-XL/122 \
|
||||
--dataset sky \
|
||||
--ae stabilityai/sd-vae-ft-mse \
|
||||
--data-path /remote-home/yeyang/sky_timelapse/sky_train/ \
|
||||
--extras 1 \
|
||||
--sample-rate 3 \
|
||||
--num-frames 16 \
|
||||
--max-image-size 256 \
|
||||
--max-train-steps 1000000 \
|
||||
--local-batch-size 5 \
|
||||
--lr 1e-4 \
|
||||
--ckpt-every 500 \
|
||||
--log-every 50 \
|
||||
--gradient-checkpointing \
|
||||
--attention_mode flash \
|
||||
--mixed-precision bf16
|
||||
@@ -0,0 +1,20 @@
|
||||
|
||||
accelerate launch \
|
||||
--config_file scripts/accelerate_configs/deepspeed_zero3_offload_config.yaml \
|
||||
opensora/train/train.py \
|
||||
--model Latte-XL/122 \
|
||||
--dataset sky \
|
||||
--ae stabilityai/sd-vae-ft-mse \
|
||||
--data-path /remote-home/yeyang/sky_timelapse/sky_train/ \
|
||||
--extras 1 \
|
||||
--sample-rate 3 \
|
||||
--num-frames 16 \
|
||||
--max-image-size 256 \
|
||||
--max-train-steps 1000000 \
|
||||
--local-batch-size 5 \
|
||||
--lr 1e-4 \
|
||||
--ckpt-every 500 \
|
||||
--log-every 50 \
|
||||
--gradient-checkpointing \
|
||||
--attention_mode flash \
|
||||
--mixed-precision bf16
|
||||
@@ -1,8 +0,0 @@
|
||||
|
||||
accelerate launch --multi_gpu --num_processes 8 --mixed_precision bf16 opensora/train/train.py \
|
||||
--model Latte-XL/122 --dataset sky \
|
||||
--ae stabilityai/sd-vae-ft-mse \
|
||||
--data-path "/remote-home/yeyang/sky_timelapse/sky_train/" --extras 1 \
|
||||
--sample-rate 3 --num-frames 16 --max-image-size 512 \
|
||||
--max-train-steps 1000000 --local-batch-size 2 --lr 1e-4 \
|
||||
--ckpt-every 500 --log-every 50 --gradient-checkpointing --attention_mode flash
|
||||
@@ -1,9 +0,0 @@
|
||||
|
||||
|
||||
accelerate launch --multi_gpu --num_processes 8 --mixed_precision bf16 opensora/train/train_with_feature.py \
|
||||
--model Latte-XL/122 --dataset sky_feature \
|
||||
--ae stabilityai/sd-vae-ft-mse \
|
||||
--data-path "/remote-home/yeyang/sky_timelapse/sky_train/" --extras 1 \
|
||||
--sample-rate 3 --num-frames 128 --max-image-size 256 \
|
||||
--max-train-steps 1000000 --local-batch-size 5 --lr 1e-4 \
|
||||
--ckpt-every 500 --log-every 50 --gradient-checkpointing --attention_mode flash
|
||||
@@ -1,9 +0,0 @@
|
||||
|
||||
|
||||
accelerate launch --multi_gpu --num_processes 8 --mixed_precision bf16 opensora/train/train_with_feature.py \
|
||||
--model Latte-XL/122 --dataset landscope_feature \
|
||||
--ae stabilityai/sd-vae-ft-mse \
|
||||
--data-path "/remote-home/yeyang/sky_timelapse/sky_train/" --extras 1 \
|
||||
--sample-rate 3 --num-frames 64 --max-image-size 512 \
|
||||
--max-train-steps 1000000 --local-batch-size 5 --lr 1e-4 \
|
||||
--ckpt-every 500 --log-every 50 --gradient-checkpointing --attention_mode flash
|
||||
Reference in New Issue
Block a user