Initial Commit based on Open-Sora-Plan-V1.2
Former-commit-id: 7a3dccf2c738eaf535e62996211c8bc5f3de5683 Update README.md Former-commit-id: aee63a3a8422e029f1550e47825ca4beb916874b Update README.md Former-commit-id: fb46c80c1a2663c09849472e93b2da6cd068a98c Update README.md Former-commit-id: 5fd1e6afe1277ccffdfeaf507477d944a6a35f03 Update README.md Former-commit-id: 1cd7d8b5df34ab9f61d9346b2647b643f78a8f5d Update README.md Former-commit-id: e27cc5d49a19e9580ba1a29d948051b918aede74 Update README.md Former-commit-id: 0ff9314bddef1dfbbf429726ed4240b823b221b3 Update README.md Former-commit-id: f295f4623448dd4ffa9be747a5cc6733cf48c663 Create Contribution_Guidelines.md Former-commit-id: 897dbd63dc6f53095e1dda3f10a86dd40e4bd263 Update README.md Former-commit-id: c652acd1fc5a003b4d6eefcfb83dfb310f5b5e81 Rename data.md to Data.md Former-commit-id: 27484f7a2d8634bd1cd9781a2f10afa7f304f5cb Update README.md Former-commit-id: 351be764d8648ac60cf170c3fe4e6ed9c544c90e reformat code Former-commit-id: ce23b280fbb419c08347ebcbf1ed4075bdf9af60 Update requirements.txt As in previous step,the three packages have been installed, these packages should be deleted here because it can not be installed by " pip install -r requirements.txt" command and will abort the command Former-commit-id: 0655fa28cf8bb761f1a3d2def62f44197b257b2c Update README.md Former-commit-id: 1dd9c945be2a170d87d568bb00e1ec30e7be592b Update README.md Former-commit-id: 6ecaba8e03d7c7f99c068a57c923f11c5456a8c9 Update Contribution_Guidelines.md Former-commit-id: dc87e459ca5a8a090800331111118acb65214f65 Update README.md Former-commit-id: be7ecc3d56f7289052fc66d535038e7111f7ac84 Update README.md Former-commit-id: 164e76cf496b1157eebea299ed58ca6c1799d70d Update README.md Former-commit-id: 3e3d674134498512b1ef1b0dd72d6e19afd6ef65 [feat]: frame_interpolation Former-commit-id: 711fc4bba80d5f051f712e3460e2c0685117cf68 Update README.md Former-commit-id: 1436d8feea7f82d3d747c632a68c47b3ea74258f fix_readme_requirements Former-commit-id: eb5a5c69d12cc412c12a4fea7f00baafd02701ca Update README.md Former-commit-id: c5a79c7e993d9e6a77c6c70efa1c0ac2bb3a063b add latte Former-commit-id: 01ba10e5d65c9d2d957472fbe7958e1b07a971e9 Update README.md Former-commit-id: 437bc5c68b5c7a85865ad97d544c4818be45cb52 first commit Former-commit-id: ec3481bc35a8120d519082dc76585428f0896470 [refactor] reformat videogpt, support training videogpt on accelerate Former-commit-id: 75385ed47fe60008b61b1bcf89f61ea696d095bc [refactor] adapt to old training code Former-commit-id: 358d362ecbc100b21ea02895cb0426cf5b386a72 Delete LICENSE.txt Former-commit-id: b10d8b2c6620e3a8412527bd03ea0adc26c981a6 Create LICENSE Former-commit-id: 369fe085e91e55b9be6165da4a1eb7f9c0cf5a7f Update README.md Former-commit-id: f1aaeca19bc9e4304961c8c903f9bf03cb42fd9f Update README.md Former-commit-id: 0f2bdd2bcd819d528f2a41a96ba93f5c3c04dc8c Update README.md Former-commit-id: 10ee64c122f28efea39fc1a4542d278683a58ce1 option to use rebased linear attention Former-commit-id: f1b39b34df5fbdef14ef3f6a0e6d0972a8570445 support for ring attention Former-commit-id: 0533c73b99217e88da121bd0f68e0949bc88016e add vae and fix bug in dit Former-commit-id: 2dd4254c22ce671d5cd5e7d22a2386b7660fbdc4 Update README.md Former-commit-id: 898d35f15ce0fd124cd48078f0a8af2764bf55d1 support latte training Former-commit-id: d471a9414842f422d1200c2fd3f3ddfcf9e97fd6 Update README.md Former-commit-id: 9fd88eb8ac5122b0999ccb0071f195aaeb0979a0 Update README.md Former-commit-id: 398cfcd7b19cf1ba827eb49fc11223f72fa93a85 Update README.md Former-commit-id: 673659495b7503ba402fbcb6c46204499761b4cf [fix] fix a bug when using ucf101_stride4x4x4 Former-commit-id: 9911403c688321db731450d9383bc02923a4be2d [refactor] remove test.ipynb Former-commit-id: e73c3a9e0d41e51a0fd755e57739424213a76312 [fix] fix a bug when using ucf101_stride4x4x4 Former-commit-id: f541e723d65ea44ae4560c68908123c7e6781bbc [refactor] rename Former-commit-id: ec317605d24223527b8c2d4b4d2ee876f86abbaf update add RGT Former-commit-id: a491111e48cec588095381eb70ffca94600ca4f7 add sample script Former-commit-id: 9ce847651bb6dba28c51ce5807e222ae2902a78a [refactor] configuration default values Former-commit-id: d7ca7685d6a8c6d015082dda241bc98ab156770d [refactor] added more methods in abstract classes Former-commit-id: a535e3a06eb766bebe7baa3d9df64b04d04d40e6 Update README.md Former-commit-id: 59a595a1e31b156500a944f244afec40988e872d [fix]: disable gradient computation to save GPU memory when reconstructing a video Former-commit-id: b7bf763e7f8800959ed82bb89f41684db216dd8e support accelerate training Former-commit-id: b32671c9991b9a9db66cb148822ccb3e8be7dc11 Update train.sh Former-commit-id: 6c4957d715eaa489691be21dd0abdb9309660e0d Update train.sh Former-commit-id: 66aa3709f80d89a30d0a57c5e033ce1ae46f998f Update README.md Former-commit-id: 604a29d1de43e0fcb90ada4dd97f5f080e37caea Update README.md Former-commit-id: d097e40998a3396f74c2bfbcf26d6ace8080d0b6 Update README.md Former-commit-id: 1a7178a61547c33a744d032302fb76ee0a3c6671 denorm fun Former-commit-id: 05707a07b14295f5e1932d0c10bb84a20a0cd328 Update README.md Former-commit-id: b3f6bb7f252505efb0ffd8195003c79206fac313 refine readme. Former-commit-id: 391d9511b72aa9c09c7ad8992ae5df8c89c88c63 complement emoji. Former-commit-id: 50679cc482d8ecf4e3083c0f5a791f195a58a855 Update README.md Former-commit-id: 29f24a819fe2d4593c48afe6ca990659784bd776 [feat]: add sit model Former-commit-id: 2eda854d6c25254b71d0105a3ed092953a9d6f68 fix: remove replicated diffusion module in sit Former-commit-id: 997cb049185421d303b14d59ab6c0603f1d1a66f fix: rename sit model filename Former-commit-id: f3b2cd7dcf644f680616eee0571db90478fede23 feat: Incorporating SiT sample Former-commit-id: 91e2931e412f8c96ef748cb2322ee956309fb6aa feat: update sample Former-commit-id: e7dc492b9b4764db28aa31cc1eede914052b4ca6 attn_mask with bf16 Former-commit-id: d9667a8c15a5344e3c777197fd6badec15dcddbd Update README.md Former-commit-id: a1cc0b26a3b156d7708e8df0cfe42aad33b1c946 Update README.md Former-commit-id: 4179ed075e68d48094655c38dbde784836fd6e0f Update README.md Former-commit-id: 36e69275598b0cff38fdc5006926e422cda069b3 [fix]: disable gradient computation to save GPU memory when reconstructing a video Former-commit-id: 06da17790b53cf593a0c264dda17c76f68d2a541 Update README.md Former-commit-id: 8e9658ed993380abc43b518fcbac21a02d8ba9ba Update README.md Former-commit-id: 8b553a4477c64b5452f8424ca6987c0fb8c111ce Update README.md Former-commit-id: 0898e4b917f5e245c4394118511bcb7639973817 Update README.md Former-commit-id: 4a893ff6177d59219b6755c4a89764ef54fc7f62 Update README.md Former-commit-id: 89f9fc8eed3ca8cc2434ec227acbb845bfbcff82 [refactor] rename train_videogpt.sh Former-commit-id: e2ea2caacaf5be046f48cf50a53ccafa7a3cc351 [docs] Modify README.md and add VQVAE documentation. Former-commit-id: a5bfe70f8a8998db969d9c4938fda123aa153bc0 fixed dit forward Former-commit-id: 4cd537fab12231f7471107762b02b36217ca42d8 videogpt inference Former-commit-id: c5d617450a8271ad3b8a5e8f76ee2d77a822e31b Update README.md Former-commit-id: 4d83f1feab7d6872aca1c6b41be95950ec3cf465 Update README.md Former-commit-id: da5507e570a27becab754ba24a0671d669b7e08e Update README.md Former-commit-id: 4a04e71636dabccbef446623674f3a514395b7f9 Update README.md Former-commit-id: 2a286e5aab48aa68e7d3f04df23ec1cdfe71c6de Update README.md Former-commit-id: f4c4b3b4b1ce3c1d0b56ba5a109cd6cc57da900d Update README.md Former-commit-id: 7af6b82b29c265e53e9c48477083b4cff0e0a3d3 Update README.md Former-commit-id: 7bc544af55c0a987d0df426848cb06cb330fd52b Update README.md Former-commit-id: 2a68a1aa399a53f58246df4f9f64dfdcdd130bcf [docs] Modify README.md to fix translation error in name "CloseGPT" Former-commit-id: dd36043df4b0408e592a82f9046f6d654a5375c3 [docs] Modify README.md to fix other grammatical errors Former-commit-id: f0de27fcc38bb4dab0eeafac225a2924080a3218 Update README.md Former-commit-id: a881ff5198e1125032418f4f02fd95d2179ffb3a Update README.md Former-commit-id: 8a191abc1903ad5998fe83149c9c9ef5c8226b9e Update README.md Former-commit-id: 3b4eb14dcd8862b8251b72f30cba523a5dc1def8 Update README.md Former-commit-id: e458366e47d4b13737a71bbf866e20ec10961ade init pos embed Former-commit-id: 28f8076136ec214c66039ead7547c9b25cfe7bfc Update README.md Former-commit-id: a1d1f07c83eb0c03d93b023b5c9162a6a3c26cd9 Update README.md Former-commit-id: deddba1f03bf697fb1252a0ce4fdb5df5bcae8de Update README.md Former-commit-id: 076e6e70e717888f24265d624c6a7a8ffa2f5d1b Update README.md Former-commit-id: 7cd398721e556db6199f1d06c7a0d1de2a9720dd [updata] updata video super resolution updata video super resolution Former-commit-id: 82397545859791d112d6f0569e33fe23437563df train script Former-commit-id: 3fd1ccf099c2deed20af50bf9556e2fc3b7a4382 Delete opensora/models/super_resolution/placeholder Former-commit-id: 8dd5a6a3c85dc28989ff95e6ad41be7fdb0f0811 Update Data.md Former-commit-id: 9531e33666f842125b331cb266eb26a3a03a4009 Update Data.md Former-commit-id: 86be6b2bf5a9be1030bb3af661a2ec85e710a5c3 commit Former-commit-id: 81359cf67248b6c594ff79f121a8a38558c1cc70 Update README.md Former-commit-id: c4d7aafa3ceb6e4d48bf85b402ae2b2ce9394e53 Update README.md Former-commit-id: bca7070fac79d5ae5c37830cd55ca1e81a289197 Update README.md Former-commit-id: b37da2202e730a4930a194a80a703b591a535adf Update __init__.py Former-commit-id: 03a45aaf60d294b7a68d8fc44132d3d671e4472b Update README.md Former-commit-id: 97fe914aaa2b9bd7c2ff5d4239381631c47e8356 Update README.md Former-commit-id: c6b1ea8f1ef01096aa8c3e5272bc9fb255b5532b Delete scripts/train_vqvae.sh Former-commit-id: 952a4ce3a3b0da159d599ff3a0a052265f48c2dd update script Former-commit-id: 43f539b68af150c45040d79918a84de1dce47c33 feature dataset Former-commit-id: 9683caae8648735552270b871de22fc540ba2b55 update train.py Former-commit-id: 844173711342f2dcc021294e87971ca39854bfe4 del use_fp16 Former-commit-id: 5424c0112e04b56d1df30ac76cbc104e848406a3 update sample.py Former-commit-id: 10d8621051d1510270c6a55abe686eac86297170 fix extract feature Former-commit-id: d4dce5ec1aaa058e452a41f15cd35fe1713f0b78 Update README.md Former-commit-id: 70f6ebf421f0830a51dcc2838c2c3783cfb67376 [Updata] updata the video super resolution updata the run.py and add README.md Former-commit-id: 1e6d6ace7a0963149e228813801210b022aceacf add CI for docker autobuild Former-commit-id: c4e2d5ff1dce8662a42f1ed6a7786855d40173f7 [refactor]: add docker development support Former-commit-id: fded3baff7915c0cfc9cec3765c271259359831c update docker scripts and configs Former-commit-id: 4567e6368f1bf413d8f6319a97a852b8289ca770 Update README.md Former-commit-id: 99b0066895af072a8887737f2b603ec7fc893ccd extract script Former-commit-id: 4139f2f68ae09695302ce49afdb7318df83cabfd [docs]:update the eval_code for calculate the FVD, clip_score, ssim, lpips, psnr Former-commit-id: 1ee226c338126fbdc5178020b12271b980a7ce0c [docs]:update the eval_code for calculate the FVD, clip_score, ssim, lpips, psnr Former-commit-id: b504623d7ec2ac0b508530d21ffc88978f8a4f71 [docs]: update the evaluation Former-commit-id: 02e3789b74daa036fbbff6d13dfc7e98372260ed Update latte.py revise the xformers inputs Former-commit-id: 60db66c912192c3fbafe55ebe16157514b884e5b Fix the memory error bug when loading metadata pickle file of vqvae dataset. Former-commit-id: 97ab243bd12915cea7aa2deecfac4b99417f78a3 Update README.md Former-commit-id: 8f7b41118a3f491d1d5b5789c53790c46b023191 Update pyproject.toml Former-commit-id: 36da5d0e950625e629aebe954f89f92827397d0d Update README.md Former-commit-id: 826cc5e9162888bed82413088c6be662c278176b Update README.md Former-commit-id: 88e9f21cfc8ec775dbc9a65f740043e91e26bd91 Update README.md Former-commit-id: 38e0e290e7a5909706c2cce2e4dd047647134fb8 [docs]:update the eval code Former-commit-id: 937f2fc87d34ab9d4724cb95a6457b54a6bf4ebc [docs]:update the eval code Former-commit-id: a8c9e6cb9e39a9e929dab34077280a8d80d85573 flash-attn train and sample Former-commit-id: e336565bd5ff2aaf4d0b4ad5f42732e89cd216b3 [refactor] add static type checking Former-commit-id: 12c4240dc28888c61f1f79243627e7cdb445c840 Update README.md Former-commit-id: 513883df1ad853c9a5e7457c364227261df17a83 Fix einops bug: module 'keras.backend' has no attribute 'is_tensor' Former-commit-id: 849f8ed815295bac78c3c10d319e6731aa26ca02 [feat] Add 2D RoPE Former-commit-id: ccae80d339e34fb23706827565b5095ae2c2f320 Update README.md Former-commit-id: 6630c22baa2340a8b55badd61472daab7177bc63 xformers and flashattn Former-commit-id: 002cad95253f7da36344237ce8c8410ffb517711 safe dit Former-commit-id: f407cab7dc0e53257972d430e873f4fd77bb039d [fix] 2d RoPE init Former-commit-id: ff5931bae6efa94675b9ef6bc25f1b76217d128e fixed attn_mask in flash-attn Former-commit-id: 5e2504f429a342b75bc7a9004cee7b3f75582ee3 typo Former-commit-id: 9e87366e906ed19726c8905afb27b5df4d4e1512 Decouple mixed_precision and gradient_accumulation to command args. Former-commit-id: 903d473d1432eb492a87efe184d03439f643b92d Fix mixed_precision bugs of latte. Former-commit-id: d70a551972e04d95444d46cdbe2bfb16ad099fcb Refactor latte. Former-commit-id: 304534269f105578097bc16ab497636ad59fd9b2 Refactor latte. Former-commit-id: 7408fd0ee16247afc3d4ba43b8c8e7dfb1091a97 Support deepspeed zero2 and zero2_offload for latte training. Former-commit-id: c87e95dd357e6fa6d6fb2dcfee781bc49c039e13 Add some comments. Former-commit-id: d5b5bd7743edde6a63dc74457bded0f8c56be1c2 Fix typos. Former-commit-id: c10330d373466f3c1ab455bfb391569b9175bc3a deepspeed Former-commit-id: 6179a4b0e7d06caed4201a27679abc64615febe6 Update README.md Former-commit-id: 582070d4f97c4a4398dcb9a6699f4ab6e980c812 Add base config. Former-commit-id: d37c551a0421d6b73dee26060b517c46d8217e4f train 1080p video Former-commit-id: 74625142ef892f9e7fa459b2f98f2f7ae5b36d6a Update README.md Former-commit-id: 87636c1dc2275c4da77c6368a0f4425bea15dc12 Update README.md Former-commit-id: 059d9e863958cfd679dbb8d365de6cd933e284fc Update pyproject.toml Former-commit-id: 5c379b6e4515ad75b89cdebbc5cd490c9a821d78 Update README.md Former-commit-id: 7a62dec060c91b02ca556451266e6f3ef28e03e7 clean script Former-commit-id: 02c61f63a8539a31516b92f5bb7c2d2e428ca7d7 Update README.md Former-commit-id: 6d41cfe906f97dbed1cea8c9ed06a1f6dc84308e Update README.md Former-commit-id: 64d147863368aeef479ad25f2e5463fdcb76de46 Update README.md Former-commit-id: 2808edf11005e04aa730971a786d1a4e3bca88b5 Update README.md Former-commit-id: 1f94f2721f35670aeae8dbfb7c0a5abd06cd2aee [feat]: Caption Refiner Caption Refiner for Video Caption Former-commit-id: 97c16bccb9979acf19fb91ae8d7b84ac4a3b4d97 [BUG]: Shorten the refined caption Shorten the refined caption using GPT-3.5 summary Former-commit-id: bb159f0d5fa928258475b2058983397ceb91af9d Fix resolution typos. Former-commit-id: 3ad55d28eaf13f9c8fd23912d2691965737527e9 clean dit Former-commit-id: 117ec4196a6f2cd83da223b993b14e28f7a693f8 Update README.md Former-commit-id: abb8ed57a29b1f66adec66d854429f36f9199540 Update README.md Former-commit-id: c2c64665d4f281e264d87c20cc1cfd38e7e5f168 [fix]: correct attention_mode to attention-mode Former-commit-id: 9957e2eebb2166b02600c6052fb54908f5d12bad Update README.md Former-commit-id: 266f9f97ea8f327fdefb2ca959c23d08b7084137 Update README.md Former-commit-id: dd00e04220ff5232c5c4503a095e409471476a51 Update README.md Former-commit-id: 5717aab628fceba311e284d1bdddeacc4c43c7c5 Create train_256.sh Former-commit-id: bf62151617feb49663f8dfe0c78aa01f41e62092 Update README.md Former-commit-id: c5eea8d3492872255a6a34d422230509d1c3531c [feat]: use accelerate on multi-node Former-commit-id: 0b12fc31f1d2a63f9da38821174ab63d9b3a2d72 Update README.md Former-commit-id: 0d7dd6233811ec3c8741affb436d8004d8c676b8 Update sample.py Former-commit-id: 6e09fc266a626f465109abc199d9fb452657929e Update interpolation.py Former-commit-id: e10e3416433e5f396aa13e7d8beaf451ff47a383 Add files via upload Former-commit-id: b707b1968fa59d85891040604e7d54bef61b4549 Update and rename Frame Interpolation.md to readme.md Former-commit-id: 87bdf1ebecb002c086497b3c47acb3f3cb2aaf34 Update readme.md Former-commit-id: e287f94838007f2eda434a46bcd250099b627097 Support deepspeed for videogpt training. Former-commit-id: 1f3dfe038845d91b81b0ecc9b6f3cabb06eed5d5 Fix config typos. Former-commit-id: 455973b57bda19379d41e59aa418421fd269281e Add hidden_size argument for videogpt config. Former-commit-id: 1be9f22767fe9c80ad90cb17184751b97aff9012 Add deepspeed script for videogpt training. Former-commit-id: 3bda2a05cb789fe785b2355a613385b3eb7abbbc use fp16 temporarily. Former-commit-id: 93381968e10aae7bbec23ec1ef40e7cb311fddf0 update videogpt. Former-commit-id: 2e211563c684a8b6ef62dfc0c4f1897224dfb58d Fix deepspeed zero loss bug. Former-commit-id: e24af415bc5d6fd38d72a24d6312f4e65d3627dd Can't fix zero loss bug. Former-commit-id: 1f32f9d889743b7961b34b823b276bfd03974191 use imageio for write video which has better compatibility. Former-commit-id: 005119dc9f78ea2a611d22a53772fd59d97d7139 Update training arguments of videogpt training. Former-commit-id: c9660af891c0dae1f51a1075ef5b2df012f65e06 Update README.md Former-commit-id: 8ec7524f4f171e650d7a25cc88ed29f7b5017454 Update train_256.sh Former-commit-id: a2dfc9a8c70845446e731c88acd222e9b2db9122 Update README.md Former-commit-id: 7e74356a3279b02d062bab9c9f361f61eb756179 Update README.md Former-commit-id: cf1c56c0058288427c1dfd651c8c0e9a981c5653 refactor dit for supporting deepspeed. Former-commit-id: e1909745cb05ea2f28f3a391c194f7656593a236 Fix typos. Former-commit-id: 6add5ee7ef39a973e91b7a7c1b3a4b0980130b88 Update README.md Former-commit-id: 2d5b6815f95e94a98847b8a0376473f01bb15d14 [bug] fix quantization loss Former-commit-id: 111fcf55f969ffe4c9be284a317ae5712570a527 del t2v Former-commit-id: 910398ca297be8a188d59c59c121857666774af1 Update sample.py Former-commit-id: eb906691abec030d7aa2078b63fc9c7d678662ed Update sample.sh Former-commit-id: b149a300f1aff53d9ab6e66a91cc2bcd37900347 Update README.md Former-commit-id: 7b96fd89eaf3743a4a9fbc995e6a2a791c734f2e del t2v Former-commit-id: 5daa2952997a29e74e2b5d235001d6d9dabf9ff6 [fix]: fix sample.sh Former-commit-id: 09916dfcfb0b80a4217016919e0394a2cb665cfd update scripts Former-commit-id: 8b2a794095f2deb9b1e8090486cb8242bf81031d Update pyproject.toml Former-commit-id: 7fb921440b608e47781d2f541b2a8d893a48193e Update README.md Former-commit-id: 34e529fd02712d4466ab2bc1a63f9bd69976b6c3 Update README.md Former-commit-id: d97edd0e714a237a54f191dcebb6fd39f73185d6 resume and compress kv Former-commit-id: 0af7d58f88c1b65b4089da6f3e5c70456614da7c refactor and fix resume bug Former-commit-id: 1b1136671b9a7e0b15b70168e2c44dbff04a22e2 Update train.py Former-commit-id: 783faf5cd86c148a713ea986ceed8527b108f2b8 Update train_t2v.py Former-commit-id: d25b39ffac4474abd40b551fe0e51c421cb7bf5e Update README.md Former-commit-id: 6729039f059a23bf71faa944e2498657ef2c7442 [docs]: fix VQVAE script path Former-commit-id: d5f5c681b8c50622a84256881d193d5803ff3c28 Update pyproject.toml Former-commit-id: 5637656a79faba1b397b56918c42022cc209e731 [feat] add casual vqvae Former-commit-id: 89087970b267908c8667984aba42b1ade2505467 Update __init__.py Former-commit-id: 7c8af2909c4549e96bc0893d09fcc53d71fb6cc7 Create clip.py Former-commit-id: e3397c567efcfeef6f58dfef2eb4251bedbbf33a Update clip.py Former-commit-id: 1ee53d152630b6acc69369be33287abfb143224d train with image Former-commit-id: 209b9a8ad2f19a50e46f9b7ec68dd781898e491a support attention_mode Former-commit-id: c72f354fbfd948e8cd4b0cc63c157bc4688c7665 Update README.md Former-commit-id: 9065d12ee867c76452ce370fb71cc83bdc01470b Update README.md Former-commit-id: 95b28706d257d7769049abe30a7121b60e39a53f t2v attention_mode Former-commit-id: 4fd8bd87e0d0a98d5d0a3201d5db9a5ba055b894 Update README.md Former-commit-id: 859c0f60dac1562b8a6bbb72b793a4709dbc3597 Update Data.md Former-commit-id: d1c72e3209769d0204efb8e7d705bdf4f22b82ea train t2v feature Former-commit-id: 7f16b162cae0e3533c8ba9aa03186a846d9e02bf scripts Former-commit-id: 047046f684c2831e68e0cf256cb46fc3790cda33 add causalvae Former-commit-id: ac936276fd3213ee1815dfe096cd64cecb601428 Create causalvideovae.md Former-commit-id: 98414c2ad7dd39f740440b2d9059140f93492e83 Rename causalvideovae.md to CausalVideoVAE.md Former-commit-id: 0a78e4193fcaec4662b7c6465a9d80643b354cd6 Update README.md Former-commit-id: 8d70a890fc4191bfc98c3aca6dd3c8a70534fb3d Update README.md Former-commit-id: a41674f5ef71ced59b374226dddfa09c15a99f25 Update CausalVideoVAE.md Former-commit-id: 1cd665f699632e9dc9357379225c085d9c1278d5 Update README.md Former-commit-id: 90d6d298eaee6255098b342b31444e7a347fc50e Update README.md Former-commit-id: f294a0a28f288ae592e7de004320d3eb5e48e945 Update README.md Former-commit-id: 02b0422fd745b4b7ec091cc6ee81d1d237245fe6 [feat] eval Former-commit-id: d2c3cf5ef8d18feb7b0544d68d9796656e90ba8d fix training bug Former-commit-id: 09a6283ddd9ab11479f30324de788bd7415702ae update model Former-commit-id: e4e24650376d9dce974b290752efb416d5061983 update vae Former-commit-id: 24298df5d374d5aaa5696f6200d4e23ae887715f fix videovae trainer Former-commit-id: 79e1feb412b6eeead3306f7f0d55a01f9b2a543e Update CausalVideoVAE.md Former-commit-id: fcde4d0ff783448c2006d6f4751a0e4f9cc23d0f Update README.md Former-commit-id: 2d9ae56309717a91e0690bd5c354fe3cbe5d5ed6 Update __init__.py Former-commit-id: 2bdc29d86ebff3d6f29c38ded57c7b0dd1e6bbdb update sample Former-commit-id: 116726b9d565c689496123d4b6e62b98400536a6 tile conv Former-commit-id: 5133615bcba221c4b86ae4e8b09b82ee5d34c66d fix reshape bugs in AttnBlock3D Former-commit-id: 299622e168a6cbee14ef2056c47cae722c20e005 tile only2d Former-commit-id: 7f31ad03fdbaac97aea51a98bd29dc7327b700c9 released v1.0.0 Former-commit-id: 8df5897a4ffc341ced45faf617687fb8ebf1286c sample pipeline Former-commit-id: 8964b16c0dd65445a20050c9a0e82d909b55eaff add tile training Former-commit-id: 216079dc925beefe1ec722a4e87e46a4e1ca56be update train script Former-commit-id: ac16f77d19488cd46130587369cd7a5ea378052b refactor vae to hf Former-commit-id: a938d3f7f962709f7ecff5e9d49c9bf1ce40d7fa release Former-commit-id: 52fe2ac6610661d6a13a08390c84a8237f37986a v1.0.0 Former-commit-id: 93f44f3b425c090d9bc92687a9c50a26b4f0d7c8 clean Former-commit-id: 56ed87088e13cdd93929e2ceedbfae693e2f013a update gradio demo Former-commit-id: 80c2cc0bcc2a7532bc2440df16c1f811b0b30516 Update and rename CausalVideoVAE.md to Report-v1.0.0.md Former-commit-id: 3b848f8de33cf4f0ed802428e9ad31d2fa26de63 Update README.md Former-commit-id: e6fb5d864ac8af8214cdc89c71b42f296dda14e7 Update README.md Former-commit-id: a61200bea2eea4fd22bd8095f192fef4c22c49b4 Update README.md Former-commit-id: a2ec90a19eacb099cb9f36c1b5dd6e24be307fae Add files via upload Former-commit-id: 1ae8512b7846e9faafdb38ca532898d7f1bdcce2 Add files via upload Former-commit-id: 292cbcfa4e4f384fe6958badc27d3067173119f9 Update Report-v1.0.0.md Former-commit-id: 92d906b340f5970a77377586d7295f46b5de99ec Update README.md Former-commit-id: 037d7d3e084d7ff426347db49c4b210a2ee3927d Update README.md Former-commit-id: 7d4118566b77e09de4a3615612a5b368c76c293e Update README.md Former-commit-id: 3210474a46845ae3a6c0bde7fb6c7f9845866628 Add files via upload Former-commit-id: a232ec2d98b245a9b502a2c49fc4f468a86fbd64 Update README.md Former-commit-id: d5ab411b2e2fd5d6abeda500895e3339167572ab Update README.md Former-commit-id: 30f61958e221c3d41c4aa5917f4511e8c0482cf9 Update README.md Former-commit-id: f8cb7f38751d7a6ef586c293fb769f5d60ad5c59 Update Report-v1.0.0.md Former-commit-id: bd9aa7991212d98a6224b855a3bfb2c12feb5950 Update Report-v1.0.0.md Former-commit-id: aea1f4a82a525d3e6e1d1a1bb7631326b294cdcc Update README.md Former-commit-id: f709d75e7a7d8a08ec60132aa906f6b880af8e58 Add files via upload Former-commit-id: 9a207435d9efac0b19771df5d2288160af1bdd6e Update README.md Former-commit-id: 9bae31c73ea902581e1ee94cfd9012efdf78d349 Update README.md Former-commit-id: 9f926abb08f156807091dd044c133788649a6bac Update Report-v1.0.0.md Former-commit-id: 7cec40420601f7da57449586508e50119bd02a61 Update README.md Former-commit-id: ce2bbf82045041495ed448b46d5f4bdba84aa740 Fix some compatibility issues Former-commit-id: 942d8598b28516369780c3519607929869b427b7 Fix bugs in inference Former-commit-id: c251a86ac7c91d6f2bb12ae645628e9cf4b83d3d fix bugs in inference Former-commit-id: e17c7a7b7704920cb86894419bf573d0fb0c06fa Update README.md Former-commit-id: c1492211ced3cdbec93ef28678a1467245e122e9 Update README.md Former-commit-id: c4a976e9b93536299b2e350454c780fec54fbe95 Update README.md Former-commit-id: bbf3cef43a129a25a80ce134a8895796e24353c6 Update README.md Former-commit-id: 5731e810e2efb7ca7eda1aa8954eb7fd260f4250 Update README.md Former-commit-id: 1b54444249fa91b29334b8fc364fb1978c25fb2d Update README.md Former-commit-id: 9c0f82ae9953b56f2540e9c7ada021e4e1bc6165 Update Report-v1.0.0.md Former-commit-id: 38b779022418cc41cdf9fc508e461f2f6299fd60 Update Report-v1.0.0.md Former-commit-id: 6ebe2c62c0904142026d3796027e95ce43afe16a Update README.md Former-commit-id: 2873d0eaedfad392c627a714448118949d7b7e13 Update Report-v1.0.0.md Former-commit-id: 400f708a080f0799e02697bb8e66d8430ffb1f56 Update Report-v1.0.0.md Former-commit-id: 37f181f34f64ca1141a1345b7c1f2af283be1cad Update README.md Former-commit-id: dc923fe2413b3be31d8d88e7dd83a931fcbf9458 Update README.md Former-commit-id: 828be4267f0795969293e4a321e4e0bfa8e1f1e6 clean Former-commit-id: a7f2c1c8b2243587cedd6e152e64298842287095 Update pyproject.toml Former-commit-id: bb037420b75303b58486ba79da9180b2bf63cf88 Update Data.md Former-commit-id: d9a5c8fbd36a34b7baf720bc27d69604ae5c9d57 add causalvae doc Former-commit-id: 4e6d9e038c8edb81f8402834bd01eeeb823924f9 Update Train_And_Eval_CausalVideoVAE.md Former-commit-id: 589657b089930379bb75f3d49063ebb72671efc6 Update Train_And_Eval_CausalVideoVAE.md Former-commit-id: 156739c35b5dda594138b2e3b1fd6ec99556af23 Update README.md Former-commit-id: 567ade18047a9cc81648997c5d9287fa8900614d 更新 README.md Former-commit-id: 42607786f3f3d0eba9336f774b0a2ae076cce793 Update README.md Former-commit-id: 88e7f2062c494c199caff468f5f14f3165f763de Create Report-v1.0.0-cn.md Former-commit-id: d484754e080bd65f6b35619b840040581fa6b69c Update README.md Former-commit-id: e386ec112337271bb9f55ea6ec872eaba94aff50 Update README.md Former-commit-id: c437a18dbec7ac6e02287565a84d75f96664ee99 Update README.md Former-commit-id: 0cc27a5b065b61f37d44dc2c90ba2782075eefb2 Update Report-v1.0.0-cn.md Former-commit-id: d5cf6aed7c1673562a6d2022c3fd7f7b16006cfd Update Data.md Former-commit-id: 15defc1a3846335fd68e18fa9b8ffbe38e3e7100 Update Report-v1.0.0.md Former-commit-id: 3c8eb75dc2045154e8654f860b1fabd7e597094b Update Report-v1.0.0-cn.md Former-commit-id: 0edac24fcaa447a534755bf3aac1f2027a491c06 Update Report-v1.0.0-cn.md Former-commit-id: 59edce70edbaed957ba40f1d95b4a5050ece12bf Update Report-v1.0.0-cn.md Former-commit-id: 83124efeaa5a8cd528a15760bdf88acc403142bd Add files via upload Former-commit-id: 943dd9a063baaa05d7f0d0bd52cbde35cf2b3d98 [formerly 5542359738243a8e948a8f08ed4e8dedf6b4b818] Former-commit-id: fbee07f6fef2ac86bc15ff66f2e2a1a68b64ed01 Update README.md Former-commit-id: 6fd60c73b6ae69d6ad9dc14c7371bd9bff086b44 [formerly 2ed5d5b7bdcd88044da26ca94237c50af7ab47dd] Former-commit-id: 443c333353963bc1ec64a4946afbe5e17f9b5a87 Update README.md Former-commit-id: 54bad83bf054a2ff574199931121c686b4e28008 [formerly 06bb190a39a9b98c8de5e385fc304a86cc8c9fb2] Former-commit-id: 23e8a235d6828d9ab7c02ef59d40fe13a46fa4b1 Update README.md Former-commit-id: c48eba0bb15d594007809d4cc605dc46ba029cec [formerly 7deb8a0decf7a9757af4475e3029d415d78d185f] Former-commit-id: 7f43bb2f1d9308bd08154171d78e9b36e00a837f Update README.md Former-commit-id: 68eaf2e6b00266cf0858b33f9b4d09681efbd2bc [formerly d8dcad250ed8357964ab8ee570b9973b45e29fcb] Former-commit-id: 75f51b3d84203be3672f6b07bb3c70ba0ae5556c Update README.md Former-commit-id: be00a17729ac889493f63fd1d649054d7980ca42 [formerly 9b4d8dcfc8e6e2abe4ca727e01561d27d1ba3968] Former-commit-id: f1b6f5013b99d0d288af0f05c46cb8300d79a8aa Update train_videoae_65x256x256.sh Former-commit-id: b2f5cfe72452dfb369aba166e4a101dfcf5758c9 [formerly 557b78ab38a61d7520e91044137f818e50ec24cb] Former-commit-id: 0e46c9f261e7f5fd4d08e3d7735c17c7975b0e72 Update train_videoae_65x512x512.sh Former-commit-id: 8e40db106efa2fd879cca42bd9ce2d9b79d777f8 [formerly 3e11781b045a838a5aa98ea75e274198f2b26a44] Former-commit-id: f3b0804a7cf063e7ff04ee57dccee0320c1f32a5 fix using pretrained bug Former-commit-id: 2dfbb0683b2f3bd1a1d619e5e4fabb5bd4c92d79 [formerly 27f352e822f732cb351d64ac5726c5df3b62c1bb] Former-commit-id: 722d60ae5ef28499c47292e0a4807a87b9658b01 Update train_t2v_feature.py Former-commit-id: 4a4f7ea2366f1dff5669d6d4834238ebd790e6e2 [formerly ca7d3158fb01f8e7228f833cea8e6741be127c2a] Former-commit-id: 389f0e7dc66826026046b8e12d7a9f8692d32e42 [docs] update docs and train.sh Former-commit-id: 1d9358e84d12863681b396c7621ae7244caa4dc2 [formerly b801491889b3abad1211225d7f07af3ae0389895] Former-commit-id: 9e6a59ae2f246b50ace0a033cbd6548660241204 [fix] fix bug in #185 Former-commit-id: d74efbd0195380ca383598c06d3d8185dd9cc9bc [formerly 0f2687266bc2271e11b2f06edfe514f466e57b0f] Former-commit-id: cb6bb234befc49b3870c5690653469a0714890c5 [docs] add evaluation detail Former-commit-id: c15a717cc61159e5f6adafb718237ab578ac81e7 [formerly 9e92772776fa4dd18772c7fec939a42ad6dfbc0a] Former-commit-id: 98c2a38af5064f27888d1b102c9fded87d2420d5 [docs] update train.sh Former-commit-id: eeb00ac046692bc97a064ec1b47c994436798ab1 [formerly 6d0fd85e1b13a7824b8181ba9ccebec2a3c76d40] Former-commit-id: 1e8e669ad9967aeeeb7622bc04a0759f348cb26f Delete assets/we_want_you.jpg Update README.md fix typo Fix typos line 24: `github -> GitHub` line 54: `a -> an` line 85: `re-organizes -> re-organize, modulizes -> modulize` line 87: `opened -> open` (modified according to the changelogs of other dates) line 94: `a -> an` [fix]: Fix variable naming errors Update README.md [docs] update inference example. [feat] add time chunk inference [docs] fix typo [refactor] fix hardcode Update LICENSE Update Report-v1.0.0.md Update pyproject.toml add 2drope and dynamic training refactor dynamic training read image from folder img training img training support newvae vae temporal tiling abs and rope compress kv and rope pi fix rope with compress update dataset mask loss multi-data fix dataset train vis update fix mask 5.15 prepare release prepare scripts fix demo 5.27 update prompt Update README.md Update README.md Create Report-v1.1.0.md Update README.md Update README.md Update README.md Update README.md Update README.md Update README.md Update README.md Update README.md Update README.md Update README.md Update README.md Update LICENSE Update Report-v1.1.0.md solve typos Update pyproject.toml Update README.md Update dataset_utils.py Update modeling_latte.py Update train_t2v.py Update train_t2v.py Update t2v_datasets.py fix wrong code Update LICENSE fix train bug fix vis [docs] update CausalVideoVAE docs Update README.md fix the bug Update gradio_web_server.py Update README.md Update gradio_utils.py Update sample_video_513.sh Rename sample_video_513.sh to sample_video_221.sh Update README.md Update Report-v1.1.0.md release v1.2.0 Update README.md Update Report-v1.2.0.md Update README.md Update pyproject.toml Update Report-v1.2.0.md Update Report-v1.2.0.md Update Report-v1.2.0.md Update t2v_datasets.py Update Report-v1.2.0.md Update Report-v1.2.0.md Update README.md Update Report-v1.2.0.md Update Report-v1.2.0.md Update README.md fix sample Delete opensora/train/train_t2v_diffusers_lora.py lora bug Update README.md Update Report-v1.2.0.md Update train_t2v_diffusers.py release Open-Sora Plan v1.2.0 i2v (#389) * gitignore * inpaint * Create condition_image_path.txt * Rename condition_image_path.txt to condition_images_path.txt * Update sample_inpaint.py * Update sample_inpaint.sh * inpaint * fix bug * Update README.md * inpainting * release v1.2.0 i2v * release v1.2.0 i2v * Update Report-v1.2.0.md * Update pipeline_inpaint_sp.py * Update sample_inpaint_ddp.py * Update sample_inpaint_sp.py * Update sample_inpaint.py * Grammar Error Correction * Grammar Error Correction --------- Co-authored-by: LinB203 <2267330597@qq.com> Update Report-v1.2.0.md add 29x480p link Update README.md Update train_inpaint.sh do not set seed [fix] fix the path typo for google/mt5-xxl in gradio_web_server.py (#405) * [fix] fix the path typo for google/mt5-xxl in gradio_web_server.py * [fix] fix the issue: the cache of pretrained mt5-xxl weights is inconsistent. --------- Co-authored-by: guangyi <guangyi.liu@mbz-h100-029.core42.ai>
This commit is contained in:
 lb203
@@ -0,0 +1,38 @@
|
||||
name: docker-build
|
||||
|
||||
on:
|
||||
workflow_dispatch:
|
||||
push:
|
||||
branches:
|
||||
- "main"
|
||||
paths:
|
||||
- "docker/Dockerfile"
|
||||
|
||||
jobs:
|
||||
build-Open-Sora:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
-
|
||||
name: Checkout
|
||||
uses: actions/checkout@v4
|
||||
-
|
||||
name: Set up QEMU
|
||||
uses: docker/setup-qemu-action@v3
|
||||
-
|
||||
name: Set up Docker Buildx
|
||||
uses: docker/setup-buildx-action@v3
|
||||
-
|
||||
name: Login to Docker Hub
|
||||
uses: docker/login-action@v3
|
||||
with:
|
||||
username: ${{ secrets.DOCKERHUB_USERNAME }}
|
||||
password: ${{ secrets.DOCKERHUB_TOKEN }}
|
||||
-
|
||||
name: Build and push Open-Sora image
|
||||
uses: docker/build-push-action@v5
|
||||
with:
|
||||
context: .
|
||||
file: ./docker/Dockerfile
|
||||
push: true
|
||||
platforms: linux/amd64, linux/arm64, linux/s390x, linux/ppc64le
|
||||
tags: ${{ secrets.DOCKERHUB_USERNAME }}/open-sora
|
||||
+49
@@ -0,0 +1,49 @@
|
||||
ucf101_stride4x4x4
|
||||
__pycache__
|
||||
*.mp4
|
||||
.ipynb_checkpoints
|
||||
*.pth
|
||||
UCF-101/
|
||||
results/
|
||||
vae
|
||||
build/
|
||||
opensora.egg-info/
|
||||
wandb/
|
||||
.idea
|
||||
*.ipynb
|
||||
*.jpg
|
||||
*.mp3
|
||||
*.safetensors
|
||||
*.mp4
|
||||
*.png
|
||||
*.gif
|
||||
*.pth
|
||||
*.pt
|
||||
cache_dir/
|
||||
wandb/
|
||||
test*
|
||||
sample_video*
|
||||
sample_image*
|
||||
512*
|
||||
720*
|
||||
1024*
|
||||
debug*
|
||||
private*
|
||||
caption*
|
||||
*deepspeed*
|
||||
revised*
|
||||
129f*
|
||||
all*
|
||||
read*
|
||||
YSH*
|
||||
*pick*
|
||||
*ysh*
|
||||
hw*
|
||||
257f*
|
||||
513f*
|
||||
taming*
|
||||
221hw*
|
||||
65x512x512
|
||||
runs/
|
||||
samples/
|
||||
*validation/
|
||||
@@ -0,0 +1,21 @@
|
||||
MIT License
|
||||
|
||||
Copyright (c) 2024 PKU-YUAN's Group (袁粒课题组-北大信工) and Rabbitpre AI
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
of this software and associated documentation files (the "Software"), to deal
|
||||
in the Software without restriction, including without limitation the rights
|
||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
copies of the Software, and to permit persons to whom the Software is
|
||||
furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all
|
||||
copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
SOFTWARE.
|
||||
@@ -0,0 +1,453 @@
|
||||
|
||||
|
||||
<h1 align="left"> <a href="">Open-Sora Plan</a></h1>
|
||||
|
||||
This project aims to create a simple and scalable repo, to reproduce [Sora](https://openai.com/sora) (OpenAI, but we prefer to call it "ClosedAI" ). We wish the open-source community can contribute to this project. Pull requests are welcome! The current code supports complete training and inference using the Huawei Ascend AI computing system. Models trained on Huawei Ascend can also output video quality comparable to industry standards.
|
||||
|
||||
本项目希望通过开源社区的力量复现Sora,由北大-兔展AIGC联合实验室共同发起,当前版本离目标差距仍然较大,仍需持续完善和快速迭代,欢迎Pull request!目前代码同时支持使用国产AI计算系统(华为昇腾)进行完整的训练和推理。基于昇腾训练出的模型,也可输出持平业界的视频质量。
|
||||
|
||||
<h5 align="left">
|
||||
|
||||
[](https://discord.gg/FkFm5M2J)
|
||||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/issues/53#issuecomment-1987226516)
|
||||
[](https://x.com/LinBin46984/status/1795018003345510687) <br>
|
||||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/blob/main/LICENSE)
|
||||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/graphs/contributors)
|
||||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/commits/main/)
|
||||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/pulls)
|
||||
[](https://github.com/PKU-YuanGroup/Video-LLaVA/issues?q=is%3Aopen+is%3Aissue)
|
||||
[](https://github.com/PKU-YuanGroup/Video-LLaVA/issues?q=is%3Aissue+is%3Aclosed) <br>
|
||||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/stargazers) 
|
||||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/network) 
|
||||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/watchers) 
|
||||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/archive/refs/heads/main.zip)
|
||||
</h5>
|
||||
<h5 align="left"> If you like our project, please give us a star ⭐ on GitHub for latest update. </h2>
|
||||
|
||||
|
||||
# 📣 News
|
||||
* **[2024.08.13]** 🎉 We are launching Open-Sora Plan v1.2.0 **I2V** model, which based on Open-Sora Plan v1.2.0. The current version supports image-to-video generation and transition generation (the starting and ending frames conditions for video generation). Checking out the Image-to-Video section in this [report](https://github.com/PKU-YuanGroup/Open-Sora-Plan/blob/main/docs/Report-v1.2.0.md#training-image-to-video-diffusion-model).
|
||||
* **[2024.07.24]** 🔥🔥🔥 v1.2.0 is here! Utilizing a 3D full attention architecture instead of 2+1D. We released a true 3D video diffusion model trained on 4s 720p. Checking out our latest [report](docs/Report-v1.2.0.md).
|
||||
* **[2024.05.27]** 🎉 We are launching Open-Sora Plan v1.1.0, which significantly improves video quality and length, and is fully open source! Please check out our latest [report](docs/Report-v1.1.0.md). Thanks to [ShareGPT4Video's](https://sharegpt4video.github.io/) capability to annotate long videos.
|
||||
* **[2024.04.09]** 🤝 Excited to share our latest exploration on metamorphic time-lapse video generation: [MagicTime](https://github.com/PKU-YuanGroup/MagicTime), which learns real-world physics knowledge from time-lapse videos.
|
||||
* **[2024.04.07]** 🎉🎉🎉 Today, we are thrilled to present Open-Sora-Plan v1.0.0, which significantly enhances video generation quality and text control capabilities. See our [report](docs/Report-v1.0.0.md). Thanks to HUAWEI NPU for supporting us.
|
||||
* **[2024.03.27]** 🚀🚀🚀 We release the report of [VideoCausalVAE](docs/CausalVideoVAE.md), which supports both images and videos. We present our reconstructed video in this demonstration as follows. The text-to-video model is on the way.
|
||||
* **[2024.03.01]** 🤗 We launched a plan to reproduce Sora, called Open-Sora Plan! Welcome to **watch** 👀 this repository for the latest updates.
|
||||
|
||||
# 😍 Gallery
|
||||
|
||||
93×1280×720 Text-to-Video Generation. The video quality has been compressed for playback on GitHub.
|
||||
|
||||
<table class="center">
|
||||
<tr>
|
||||
<td><video src="https://github.com/user-attachments/assets/1c84bc92-d585-46c9-ae7c-e5f79cefea88" autoplay></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
# 😮 Highlights
|
||||
|
||||
Open-Sora Plan shows excellent performance in video generation.
|
||||
|
||||
### 🔥 High performance CausalVideoVAE, but with fewer training cost
|
||||
- High compression ratio with excellent performance, capable of **compressing videos by 256 times (4×8×8)**. Causal convolution supports simultaneous inference of images and videos but only need **1 node to train**.
|
||||
|
||||
### 🚀 Video Diffusion Model based on 3D attention, joint learning of spatiotemporal features.
|
||||
- With a **3D full attention architecture** instead of a 2+1D model, 3D attention can better capture joint spatial and temporal features.
|
||||
|
||||
<p align="center">
|
||||
<img src="https://s21.ax1x.com/2024/07/22/pk7cob8.png" width="650" style="margin-bottom: 0.2;"/>
|
||||
<p>
|
||||
|
||||
# 🤗 Demo
|
||||
|
||||
### Gradio Web UI
|
||||
|
||||
Highly recommend trying out our web demo by the following command.
|
||||
|
||||
```bash
|
||||
python -m opensora.serve.gradio_web_server --model_path "path/to/model" --ae_path "path/to/causalvideovae"
|
||||
```
|
||||
|
||||
### ComfyUI
|
||||
|
||||
Coming soon...
|
||||
|
||||
# 🐳 Resource
|
||||
|
||||
| Version | Architecture | Diffusion Model | CausalVideoVAE | Data|
|
||||
|:---|:---|:---|:---|:---|
|
||||
| v1.2.0 | 3D | [93x720p](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.2.0/tree/main/93x720p), [29x720p](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.2.0/tree/main/29x720p)[1], [93x480p](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.2.0/tree/main/93x480p)[1,2], [29x480p](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.2.0/tree/main/29x480p), [1x480p](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.2.0/tree/main/1x480p), [93x480p_i2v](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.2.0/tree/main/93x480p_i2v) | [Anysize](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.2.0/tree/main/vae)| [Annotations](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.2.0) |
|
||||
| v1.1.0 | 2+1D | [221x512x512](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.1.0/tree/main/221x512x512), [65x512x512](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.1.0/tree/main/65x512x512) |[Anysize](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.1.0/tree/main/vae) |[Data and Annotations](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.1.0)|
|
||||
| v1.0.0 | 2+1D | [65x512x512](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.0.0/tree/main/65x512x512), [65x256x256](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.0.0/tree/main/65x256x256), [17x256x256](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.0.0/tree/main/17x256x256) | [Anysize](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.0.0/tree/main/vae) | [Data and Annotations](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.0.0)|
|
||||
|
||||
> [1] Please note that the weights for v1.2.0 29×720p and 93×480p were trained on Panda70M and have not undergone final high-quality data fine-tuning, so they may produce watermarks.
|
||||
|
||||
> [2] We fine-tuned 3.5k steps from 93×720p to get 93×480p for community research use.
|
||||
|
||||
> [!Warning]
|
||||
>
|
||||
> <div align="left">
|
||||
> <b>
|
||||
> 🚨 For version 1.2.0, we no longer support 2+1D models.
|
||||
> </b>
|
||||
> </div>
|
||||
|
||||
# ⚙️ Requirements and Installation
|
||||
|
||||
1. Clone this repository and navigate to Open-Sora-Plan folder
|
||||
```
|
||||
git clone https://github.com/PKU-YuanGroup/Open-Sora-Plan
|
||||
cd Open-Sora-Plan
|
||||
```
|
||||
2. Install required packages
|
||||
We recommend the requirements as follows.
|
||||
* Python >= 3.8
|
||||
* Pytorch >= 2.1.0
|
||||
* CUDA Version >= 11.7
|
||||
```
|
||||
conda create -n opensora python=3.8 -y
|
||||
conda activate opensora
|
||||
pip install -e .
|
||||
```
|
||||
3. Install additional packages for training cases
|
||||
```
|
||||
pip install -e ".[train]"
|
||||
```
|
||||
4. Install optional requirements such as static type checking:
|
||||
```
|
||||
pip install -e '.[dev]'
|
||||
```
|
||||
|
||||
# 🗝️ Training & Validating
|
||||
|
||||
## 🗜️ CausalVideoVAE
|
||||
|
||||
### Data prepare
|
||||
The organization of the training data is easy. We only need to put all the videos recursively in a directory. This makes the training more convenient when using multiple datasets.
|
||||
``` shell
|
||||
Training Dataset
|
||||
|——sub_dataset1
|
||||
|——sub_sub_dataset1
|
||||
|——video1.mp4
|
||||
|——video2.mp4
|
||||
......
|
||||
|——sub_sub_dataset2
|
||||
|——video3.mp4
|
||||
|——video4.mp4
|
||||
......
|
||||
|——sub_dataset2
|
||||
|——video5.mp4
|
||||
|——video6.mp4
|
||||
......
|
||||
|——video7.mp4
|
||||
|——video8.mp4
|
||||
```
|
||||
### Training
|
||||
``` shell
|
||||
bash scripts/causalvae/train.sh
|
||||
```
|
||||
We introduce the important args for training.
|
||||
| Argparse | Usage |
|
||||
|:---|:---|
|
||||
|_Training size_||
|
||||
|`--num_frames`|The number of using frames for training videos|
|
||||
|`--resolution`|The resolution of the input to the VAE|
|
||||
|`--batch_size`|The local batch size in each GPU|
|
||||
|`--sample_rate`|The frame interval of when loading training videos|
|
||||
|_Data processing_||
|
||||
|`--video_path`|/path/to/dataset|
|
||||
|_Load weights_||
|
||||
|`--model_config`|/path/to/config.json The model config of VAE. If you want to train from scratch use this parameter.|
|
||||
|`--pretrained_model_name_or_path`|A directory containing a model checkpoint and its config. Using this parameter will only load its weight but not load the state of the optimizer|
|
||||
|`--resume_from_checkpoint`|/path/to/checkpoint It will resume the training process from the checkpoint including the weight and the optimizer.|
|
||||
### Inference
|
||||
``` shell
|
||||
bash scripts/causalvae/rec_video.sh
|
||||
```
|
||||
We introduce the important args for inference.
|
||||
| Argparse | Usage |
|
||||
|:---|:---|
|
||||
|_Ouoput video size_||
|
||||
|`--num_frames`|The number of frames of generated videos|
|
||||
|`--height`|The resolution of generated videos|
|
||||
|`--width`|The resolution of generated videos|
|
||||
|_Data processing_||
|
||||
|`--video_path`|The path to the original video|
|
||||
|`--rec_path`|The path to the generated video|
|
||||
|_Load weights_||
|
||||
|`--ae_path`|/path/to/model_dir. A directory containing the checkpoint of VAE is used for inference and its model config.json|
|
||||
|_Other_||
|
||||
|`--enable_tilintg`|Use tiling to deal with videos of high resolution and long duration|
|
||||
|`--save_memory`|Save memory to inference but lightly influence quality|
|
||||
|
||||
|
||||
### Evaluation
|
||||
|
||||
|
||||
For evaluation, you should save the original video clips by using `--output_origin`.
|
||||
``` shell
|
||||
bash scripts/causalvae/prepare_eval.sh
|
||||
```
|
||||
We introduce the important args for inference.
|
||||
| Argparse | Usage |
|
||||
|:---|:---|
|
||||
|_Ouoput video size_||
|
||||
|`--num_frames`|The number of frames of generated videos|
|
||||
|`--resolution`|The resolution of generated videos|
|
||||
|_Data processing_||
|
||||
|`--real_video_dir`|The directory of the original videos.|
|
||||
|`--generated_video_dir`|The directory of the generated videos.|
|
||||
|_Load weights_||
|
||||
|`--ckpt`|/path/to/model_dir. A directory containing the checkpoint of VAE is used for inference and its model config.|
|
||||
|_Other_||
|
||||
|`--enable_tilintg`|Use tiling to deal with videos of high resolution and long time.|
|
||||
|`--output_origin`|Output the original video clips, fed into the VAE.|
|
||||
|
||||
|
||||
Then, we begin to eval. We introduce the important args in the script for evaluation.
|
||||
``` shell
|
||||
bash scripts/causalvae/eval.sh
|
||||
```
|
||||
| Argparse | Usage |
|
||||
|:---|:---|
|
||||
|`--metric`|The metric, such as psnr, ssim, lpips|
|
||||
|`--real_video_dir`|The directory of the original videos.|
|
||||
|`--generated_video_dir`|The directory of the generated videos.|
|
||||
|
||||
## 📜 Text-to-Video
|
||||
|
||||
### Data prepare
|
||||
We use a `data.txt` file to specify all the training data. Each line in the file consists of `DATA_ROOT` and `DATA_JSON`. The example of `data.txt` is as follows.
|
||||
```
|
||||
/path/to/data_root_1,/path/to/data_json_1.json
|
||||
/path/to/data_root_2,/path/to/data_json_2.json
|
||||
...
|
||||
```
|
||||
Then, we introduce the format of the annotation json file. The absolute data path is the concatenation of `DATA_ROOT` and the `"path"` field in the annotation json file.
|
||||
#### For image
|
||||
The format of image annotation file is as follows.
|
||||
```
|
||||
[
|
||||
{
|
||||
"path": "00168/001680102.jpg",
|
||||
"cap": [
|
||||
"xxxxx."
|
||||
],
|
||||
"resolution": {
|
||||
"height": 512,
|
||||
"width": 683
|
||||
}
|
||||
},
|
||||
...
|
||||
]
|
||||
```
|
||||
|
||||
#### For video
|
||||
The format of video annotation file is as follows. More details refer to [HF dataset](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.2.0).
|
||||
```
|
||||
[
|
||||
{
|
||||
"path": "panda70m_part_5565/qLqjjDhhD5Q/qLqjjDhhD5Q_segment_0.mp4",
|
||||
"cap": [
|
||||
"A man and a woman are sitting down on a news anchor talking to each other."
|
||||
],
|
||||
"resolution": {
|
||||
"height": 720,
|
||||
"width": 1280
|
||||
},
|
||||
"fps": 29.97002997002997,
|
||||
"duration": 11.444767
|
||||
},
|
||||
...
|
||||
]
|
||||
```
|
||||
|
||||
### Training
|
||||
```
|
||||
bash scripts/text_condition/gpu/train_t2v.sh
|
||||
```
|
||||
|
||||
We introduce some key parameters in order to customize your training process.
|
||||
|
||||
| Argparse | Usage |
|
||||
|:---|:---|
|
||||
|_Training size_||
|
||||
|`--num_frames 61`|To train videos of different durations, e.g, 29, 61, 93, 125...|
|
||||
|`--max_height 640`|To train videos of different resolutions|
|
||||
|`--max_width 480`|To train videos of different resolutions|
|
||||
|_Data processing_||
|
||||
|`--data /path/to/data.txt`|Specify your training data.|
|
||||
|`--speed_factor 1.25`|To accelerate 1.25x videos. |
|
||||
|`--drop_short_ratio 1.0`|Do not want to train on videos of dynamic durations, discard all video data with frame counts not equal to `--num_frames`|
|
||||
|`--group_frame`|If you want to train with videos of dynamic durations, we highly recommend specifying `--group_frame` as well. It improves computational efficiency during training.|
|
||||
|_Multi-stage transfer learning_||
|
||||
|`--interpolation_scale_h 1.0`|When training a base model, such as 240p (`--max_height 240`, `--interpolation_scale_h 1.0`) , and you want to initialize higher resolution models like 480p (height 480) from 240p's weights, you need to adjust `--max_height 480`, `--interpolation_scale_h 2.0`, and set `--pretrained` to your 240p weights path (path/to/240p/xxx.safetensors).|
|
||||
|`--interpolation_scale_w 1.0`|Same as `--interpolation_scale_h 1.0`|
|
||||
|_Load weights_||
|
||||
|`--pretrained`|This is typically used for loading pretrained weights across stages, such as using 240p weights to initialize 480p training. Or when switching datasets and you do not want the previous optimizer state.|
|
||||
|`--resume_from_checkpoint`|It will resume the training process from the latest checkpoint in `--output_dir`. Typically, we set `--resume_from_checkpoint="latest"`, which is useful in cases of unexpected interruptions during training.|
|
||||
|_Sequence Parallelism_||
|
||||
|`--sp_size 8 --train_sp_batch_size 2`|It means running a batch size of 2 across 8 GPUs (8 GPUs on the same node).|
|
||||
|
||||
> [!Warning]
|
||||
> <div align="left">
|
||||
> <b>
|
||||
> 🚨 We have two ways to load weights: `--pretrained` and `--resume_from_checkpoint`. The latter will override the former.
|
||||
> </b>
|
||||
> </div>
|
||||
|
||||
### Inference
|
||||
|
||||
We provide multiple inference scripts to support various requirements. We recommend configuration `--guidance_scale 7.5 --num_sampling_steps 100 --sample_method EulerAncestralDiscrete` for sampling.
|
||||
|
||||
**Inference on 93×720p**, we report speed on H100.
|
||||
|
||||
| Size | 1 GPU | 8 GPUs (sp) |
|
||||
|---|---|---|
|
||||
|29×720p|420s/100step|80s/100step|
|
||||
|93×720p|3400s/100step|450s/100step|
|
||||
|
||||
#### 🖥️ 1 GPU
|
||||
If you only have one GPU, it will perform inference on each sample sequentially, one at a time.
|
||||
```
|
||||
bash scripts/text_condition/gpu/sample_t2v.sh
|
||||
```
|
||||
|
||||
#### 🖥️🖥️ Multi-GPUs
|
||||
If you want to batch infer a large number of samples, each GPU will infer one sample.
|
||||
```
|
||||
bash scripts/text_condition/gpu/sample_t2v_ddp.sh
|
||||
```
|
||||
|
||||
#### 🖥️🖥️ Multi-GPUs & Sequence Parallelism
|
||||
If you want to quickly infer one sample, it will utilize all GPUs simultaneously to infer that sample.
|
||||
```
|
||||
bash scripts/text_condition/gpu/sample_t2v_sp.sh
|
||||
```
|
||||
|
||||
## 🖼️ Image-to-Video
|
||||
|
||||
### Data prepare
|
||||
Same as Text-to-Video.
|
||||
|
||||
### Training
|
||||
```
|
||||
bash scripts/text_condition/gpu/train_inpaint.sh
|
||||
```
|
||||
|
||||
In addition to the parameters shared with the Text-to-Video mode, there are some unique parameters specific to the Image-to-Video mode that you need to be aware of.
|
||||
|
||||
| Argparse | Usage |
|
||||
| :---------------- | :----------------------------------------------------------- |
|
||||
| _Training size_ | |
|
||||
| `--use_vae_preprocessed_mask` | Whether to use VAE (Variational Autoencoder) to encode the mask in order to achieve frame-level mask alignment. |
|
||||
| _Data processing_ | |
|
||||
| `--i2v_ratio 0.5` | The proportion of training data allocated to executing the Image-to-Video task. |
|
||||
| `--transition_ratio 0.4 ` | The proportion of training data allocated to executing the transition task. |
|
||||
| ` --v2v_ratio 0.1 ` | The proportion of training data allocated to executing the video continuation task. |
|
||||
| `--default_text_ratio 0.5` | When training with CFG (Classifier-Free Guidance) enabled, a portion of the text is replaced with default text, while another portion is set to an empty string. |
|
||||
| _Load weights_ | |
|
||||
| `--pretrained_transformer_model_path ` | This parameter functions the same as the `--pretrained` parameter. |
|
||||
|
||||
### Inference
|
||||
|
||||
In the current version, we have only open-sourced the 480p version of the Image-to-Video (I2V) model. We recommend configuration `--guidance_scale 7.5 --num_sampling_steps 100 --sample_method PNDM` for sampling. Please note that due to the addition of frame-controllable fine-tuning, using the other samplers may not yield satisfactory results.
|
||||
|
||||
**Inference on 93×480p**, we report speed on H100.
|
||||
|
||||
| Size | 1 GPU | 8 GPUs (sp) |
|
||||
| ------- | ------------ | ----------- |
|
||||
| 93×480p | 427s/100step | 81s/100step |
|
||||
|
||||
Before inference, you need to create two text files: one named `prompt.txt` and another named `conditional_images_path.txt`. Each line of text in `prompt.txt` should correspond to the paths on each line in `conditional_images_path.txt`.
|
||||
|
||||
For example, if the content of `prompt.txt` is:
|
||||
|
||||
```
|
||||
this is a prompt of i2v task.
|
||||
this is a prompt of transition task.
|
||||
```
|
||||
|
||||
Then the content of conditional_images_path should be:
|
||||
|
||||
```
|
||||
/path/to/image_0.png
|
||||
/path/to/image_1_0.png,/path/to/image_1_1.png
|
||||
```
|
||||
|
||||
This means we will execute a image-to-video task using `/path/to/image_0.png` and "this is a prompt of i2v task." For the transition task, we'll use `/path/to/image_1_0.png` and `/path/to/image_1_1.png` (note that these two paths are separated by a comma without any spaces) along with "this is a prompt of transition task."
|
||||
|
||||
After creating the files, make sure to specify their paths in the `sample_inpaint.sh` script.
|
||||
|
||||
#### 🖥️ 1 GPU
|
||||
|
||||
If you only have one GPU, it will perform inference on each sample sequentially, one at a time.
|
||||
```
|
||||
bash scripts/text_condition/gpu/sample_inpaint.sh
|
||||
```
|
||||
#### 🖥️🖥️ Multi-GPUs
|
||||
If you want to batch infer a large number of samples, each GPU will infer one sample.
|
||||
```
|
||||
bash scripts/text_condition/gpu/sample_inpaint_ddp.sh
|
||||
```
|
||||
|
||||
#### 🖥️🖥️ Multi-GPUs & Sequence Parallelism
|
||||
If you want to quickly infer one sample, it will utilize all GPUs simultaneously to infer that sample.
|
||||
```
|
||||
bash scripts/text_condition/gpu/sample_inpaint_sp.sh
|
||||
```
|
||||
|
||||
# 💡 How to Contribute
|
||||
We greatly appreciate your contributions to the Open-Sora Plan open-source community and helping us make it even better than it is now!
|
||||
|
||||
For more details, please refer to the [Contribution Guidelines](docs/Contribution_Guidelines.md)
|
||||
|
||||
|
||||
|
||||
|
||||
# 👍 Acknowledgement
|
||||
* [Latte](https://github.com/Vchitect/Latte): It is an wonderful 2+1D video generated model.
|
||||
* [PixArt-alpha](https://github.com/PixArt-alpha/PixArt-alpha): Fast Training of Diffusion Transformer for Photorealistic Text-to-Image Synthesis.
|
||||
* [ShareGPT4Video](https://github.com/InternLM/InternLM-XComposer/tree/main/projects/ShareGPT4Video): Improving Video Understanding and Generation with Better Captions.
|
||||
* [VideoGPT](https://github.com/wilson1yan/VideoGPT): Video Generation using VQ-VAE and Transformers.
|
||||
* [DiT](https://github.com/facebookresearch/DiT): Scalable Diffusion Models with Transformers.
|
||||
* [FiT](https://github.com/whlzy/FiT): Flexible Vision Transformer for Diffusion Model.
|
||||
* [Positional Interpolation](https://arxiv.org/abs/2306.15595): Extending Context Window of Large Language Models via Positional Interpolation.
|
||||
|
||||
|
||||
# 🔒 License
|
||||
* See [LICENSE](LICENSE) for details.
|
||||
|
||||
<!--
|
||||
## ✨ Star History
|
||||
|
||||
[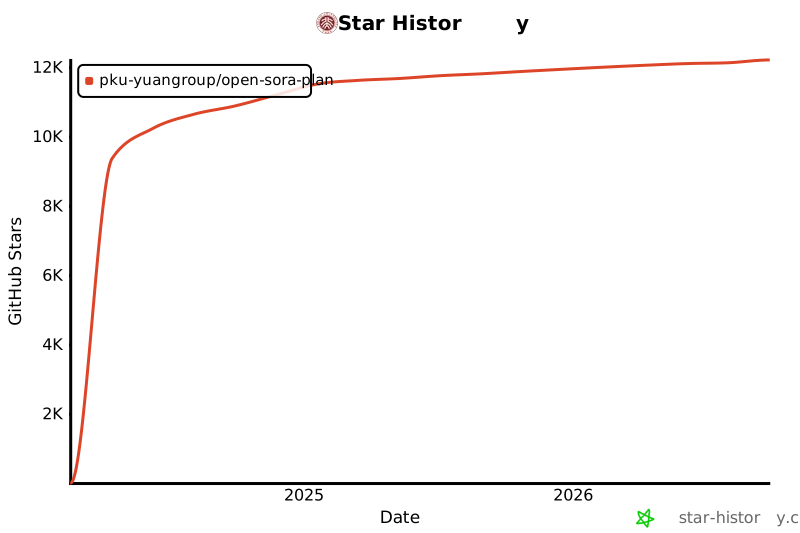](https://star-history.com/#PKU-YuanGroup/Open-Sora-Plan&Date)
|
||||
-->
|
||||
|
||||
|
||||
# ✏️ Citing
|
||||
|
||||
## BibTeX
|
||||
|
||||
```bibtex
|
||||
@software{pku_yuan_lab_and_tuzhan_ai_etc_2024_10948109,
|
||||
author = {PKU-Yuan Lab and Tuzhan AI etc.},
|
||||
title = {Open-Sora-Plan},
|
||||
month = apr,
|
||||
year = 2024,
|
||||
publisher = {GitHub},
|
||||
doi = {10.5281/zenodo.10948109},
|
||||
url = {https://doi.org/10.5281/zenodo.10948109}
|
||||
}
|
||||
```
|
||||
## Latest DOI
|
||||
|
||||
[](https://zenodo.org/records/10948109)
|
||||
|
||||
# 🤝 Community contributors
|
||||
|
||||
<a href="https://github.com/PKU-YuanGroup/Open-Sora-Plan/graphs/contributors">
|
||||
<img src="https://contrib.rocks/image?repo=PKU-YuanGroup/Open-Sora-Plan" />
|
||||
</a>
|
||||
|
||||
@@ -0,0 +1,21 @@
|
||||
MIT License
|
||||
|
||||
Copyright (c) 2024 SimonLee
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
of this software and associated documentation files (the "Software"), to deal
|
||||
in the Software without restriction, including without limitation the rights
|
||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
copies of the Software, and to permit persons to whom the Software is
|
||||
furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all
|
||||
copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
SOFTWARE.
|
||||
@@ -0,0 +1,87 @@
|
||||
# Docker4ML
|
||||
|
||||
Useful docker scripts for ML development.
|
||||
[https://github.com/SimonLeeGit/Docker4ML](https://github.com/SimonLeeGit/Docker4ML)
|
||||
|
||||
## Build Docker Image
|
||||
|
||||
```bash
|
||||
bash docker_build.sh
|
||||
```
|
||||
|
||||

|
||||
|
||||
## Run Docker Container as Development Environment
|
||||
|
||||
```bash
|
||||
bash docker_run.sh
|
||||
```
|
||||
|
||||

|
||||
|
||||
## Custom Docker Config
|
||||
|
||||
### Config [setup_env.sh](./setup_env.sh)
|
||||
|
||||
You can modify this file to custom your settings.
|
||||
|
||||
```bash
|
||||
TAG=ml:dev
|
||||
BASE_TAG=nvcr.io/nvidia/pytorch:23.12-py3
|
||||
```
|
||||
|
||||
#### TAG
|
||||
|
||||
Your built docker image tag, you can set it as what you what.
|
||||
|
||||
#### BASE_TAG
|
||||
|
||||
The base docker image tag for your built docker image, here we use nvidia pytorch images.
|
||||
You can check it from [https://catalog.ngc.nvidia.com/orgs/nvidia/containers/pytorch/tags](https://catalog.ngc.nvidia.com/orgs/nvidia/containers/pytorch/tags)
|
||||
|
||||
Also, you can use other docker image as base, such as: [ubuntu](https://hub.docker.com/_/ubuntu/tags)
|
||||
|
||||
### USER_NAME
|
||||
|
||||
Your user name used in docker container.
|
||||
|
||||
### USER_PASSWD
|
||||
|
||||
Your user password used in docker container.
|
||||
|
||||
### Config [requirements.txt](./requirements.txt)
|
||||
|
||||
You can add your default installed python libraries here.
|
||||
|
||||
```txt
|
||||
transformers==4.27.1
|
||||
```
|
||||
|
||||
By default, it has some libs installed, you can check it from [https://docs.nvidia.com/deeplearning/frameworks/pytorch-release-notes/rel-24-01.html](https://docs.nvidia.com/deeplearning/frameworks/pytorch-release-notes/rel-24-01.html)
|
||||
|
||||
### Config [packages.txt](./packages.txt)
|
||||
|
||||
You can add your default apt-get installed packages here.
|
||||
|
||||
```txt
|
||||
wget
|
||||
curl
|
||||
git
|
||||
```
|
||||
|
||||
### Config [ports.txt](./ports.txt)
|
||||
|
||||
You can add some ports enabled for docker container here.
|
||||
|
||||
```txt
|
||||
-p 6006:6006
|
||||
-p 8080:8080
|
||||
```
|
||||
|
||||
### Config [postinstallscript.sh](./postinstallscript.sh)
|
||||
|
||||
You can add your custom script to run when build docker image.
|
||||
|
||||
## Q&A
|
||||
|
||||
If you have any use problems, please contact to <simonlee235@gmail.com>.
|
||||
Executable
BIN

Binary file not shown.
|
After Width: | Height: | Size: 63 KiB |
@@ -0,0 +1,8 @@
|
||||
#!/usr/bin/env bash
|
||||
|
||||
WORK_DIR=$(dirname "$(readlink -f "$0")")
|
||||
cd $WORK_DIR
|
||||
|
||||
source setup_env.sh
|
||||
|
||||
docker build -t $TAG --build-arg BASE_TAG=$BASE_TAG --build-arg USER_NAME=$USER_NAME --build-arg USER_PASSWD=$USER_PASSWD . -f dockerfile.base
|
||||
@@ -0,0 +1,45 @@
|
||||
#!/usr/bin/env bash
|
||||
|
||||
WORK_DIR=$(dirname "$(readlink -f "$0")")
|
||||
source $WORK_DIR/setup_env.sh
|
||||
|
||||
RUNNING_IDS="$(docker ps --filter ancestor=$TAG --format "{{.ID}}")"
|
||||
|
||||
if [ -n "$RUNNING_IDS" ]; then
|
||||
# Initialize an array to hold the container IDs
|
||||
declare -a container_ids=($RUNNING_IDS)
|
||||
|
||||
# Get the first container ID using array indexing
|
||||
ID=${container_ids[0]}
|
||||
|
||||
# Print the first container ID
|
||||
echo ' '
|
||||
echo "The running container ID is: $ID, enter it!"
|
||||
else
|
||||
echo ' '
|
||||
echo "Not found running containers, run it!"
|
||||
|
||||
# Run a new docker container instance
|
||||
ID=$(docker run \
|
||||
--rm \
|
||||
--gpus all \
|
||||
-itd \
|
||||
--ipc=host \
|
||||
--ulimit memlock=-1 \
|
||||
--ulimit stack=67108864 \
|
||||
-e DISPLAY=$DISPLAY \
|
||||
-v /tmp/.X11-unix/:/tmp/.X11-unix/ \
|
||||
-v $PWD:/home/$USER_NAME/workspace \
|
||||
-w /home/$USER_NAME/workspace \
|
||||
$(cat $WORK_DIR/ports.txt) \
|
||||
$TAG)
|
||||
fi
|
||||
|
||||
docker logs $ID
|
||||
|
||||
echo ' '
|
||||
echo ' '
|
||||
echo '========================================='
|
||||
echo ' '
|
||||
|
||||
docker exec -it $ID bash
|
||||
@@ -0,0 +1,24 @@
|
||||
ARG BASE_TAG
|
||||
FROM ${BASE_TAG}
|
||||
ARG USER_NAME=myuser
|
||||
ARG USER_PASSWD=111111
|
||||
ARG DEBIAN_FRONTEND=noninteractive
|
||||
|
||||
# Pre-install packages, pip install requirements and run post install script.
|
||||
COPY packages.txt .
|
||||
COPY requirements.txt .
|
||||
COPY postinstallscript.sh .
|
||||
RUN apt-get update && apt-get install -y sudo $(cat packages.txt)
|
||||
RUN pip install --no-cache-dir -r requirements.txt
|
||||
RUN bash postinstallscript.sh
|
||||
|
||||
# Create a new user and group using the username argument
|
||||
RUN groupadd -r ${USER_NAME} && useradd -r -m -g${USER_NAME} ${USER_NAME}
|
||||
RUN echo "${USER_NAME}:${USER_PASSWD}" | chpasswd
|
||||
RUN usermod -aG sudo ${USER_NAME}
|
||||
USER ${USER_NAME}
|
||||
ENV USER=${USER_NAME}
|
||||
WORKDIR /home/${USER_NAME}/workspace
|
||||
|
||||
# Set the prompt to highlight the username
|
||||
RUN echo "export PS1='\[\033[01;32m\]\u\[\033[00m\]@\[\033[01;34m\]\h\[\033[00m\]:\[\033[01;36m\]\w\[\033[00m\]\$'" >> /home/${USER_NAME}/.bashrc
|
||||
@@ -0,0 +1,3 @@
|
||||
wget
|
||||
curl
|
||||
git
|
||||
@@ -0,0 +1 @@
|
||||
-p 6006:6006
|
||||
@@ -0,0 +1,3 @@
|
||||
#!/usr/bin/env bash
|
||||
# this script will run when build docker image.
|
||||
|
||||
@@ -0,0 +1,40 @@
|
||||
setuptools>=61.0
|
||||
torch==2.0.1
|
||||
torchvision==0.15.2
|
||||
transformers==4.32.0
|
||||
albumentations==1.4.0
|
||||
av==11.0.0
|
||||
decord==0.6.0
|
||||
einops==0.3.0
|
||||
fastapi==0.110.0
|
||||
accelerate==0.21.0
|
||||
gdown==5.1.0
|
||||
h5py==3.10.0
|
||||
idna==3.6
|
||||
imageio==2.34.0
|
||||
matplotlib==3.7.5
|
||||
numpy==1.24.4
|
||||
omegaconf==2.1.1
|
||||
opencv-python==4.9.0.80
|
||||
opencv-python-headless==4.9.0.80
|
||||
pandas==2.0.3
|
||||
pillow==10.2.0
|
||||
pydub==0.25.1
|
||||
pytorch-lightning==1.4.2
|
||||
pytorchvideo==0.1.5
|
||||
PyYAML==6.0.1
|
||||
regex==2023.12.25
|
||||
requests==2.31.0
|
||||
scikit-learn==1.3.2
|
||||
scipy==1.10.1
|
||||
six==1.16.0
|
||||
tensorboard==2.14.0
|
||||
test-tube==0.7.5
|
||||
timm==0.9.16
|
||||
torchdiffeq==0.2.3
|
||||
torchmetrics==0.5.0
|
||||
tqdm==4.66.2
|
||||
urllib3==2.2.1
|
||||
uvicorn==0.27.1
|
||||
diffusers==0.24.0
|
||||
scikit-video==1.1.11
|
||||
Executable
BIN

Binary file not shown.
|
After Width: | Height: | Size: 86 KiB |
@@ -0,0 +1,11 @@
|
||||
# Docker tag for new build image
|
||||
TAG=open_sora_plan:dev
|
||||
|
||||
# Base docker image tag used by docker build
|
||||
BASE_TAG=nvcr.io/nvidia/pytorch:23.05-py3
|
||||
|
||||
# User name used in docker container
|
||||
USER_NAME=developer
|
||||
|
||||
# User password used in docker container
|
||||
USER_PASSWD=666666
|
||||
@@ -0,0 +1,87 @@
|
||||
# Contributing to the Open-Sora Plan Community
|
||||
|
||||
The Open-Sora Plan open-source community is a collaborative initiative driven by the community, emphasizing a commitment to being free and void of exploitation. Organized spontaneously by community members, we invite you to contribute to the Open-Sora Plan open-source community and help elevate it to new heights!
|
||||
|
||||
## Submitting a Pull Request (PR)
|
||||
|
||||
As a contributor, before submitting your request, kindly follow these guidelines:
|
||||
|
||||
1. Start by checking the [Open-Sora Plan GitHub](https://github.com/PKU-YuanGroup/Open-Sora-Plan/pulls) to see if there are any open or closed pull requests related to your intended submission. Avoid duplicating existing work.
|
||||
|
||||
2. [Fork](https://github.com/PKU-YuanGroup/Open-Sora-Plan/fork) the [open-sora plan](https://github.com/PKU-YuanGroup/Open-Sora-Plan) repository and download your forked repository to your local machine.
|
||||
|
||||
```bash
|
||||
git clone [your-forked-repository-url]
|
||||
```
|
||||
|
||||
3. Add the original Open-Sora Plan repository as a remote to sync with the latest updates:
|
||||
|
||||
```bash
|
||||
git remote add upstream https://github.com/PKU-YuanGroup/Open-Sora-Plan
|
||||
```
|
||||
|
||||
4. Sync the code from the main repository to your local machine, and then push it back to your forked remote repository.
|
||||
|
||||
```
|
||||
# Pull the latest code from the upstream branch
|
||||
git fetch upstream
|
||||
|
||||
# Switch to the main branch
|
||||
git checkout main
|
||||
|
||||
# Merge the updates from the upstream branch into main, synchronizing the local main branch with the upstream
|
||||
git merge upstream/main
|
||||
|
||||
# Additionally, sync the local main branch to the remote branch of your forked repository
|
||||
git push origin main
|
||||
```
|
||||
|
||||
|
||||
> Note: Sync the code from the main repository before each submission.
|
||||
|
||||
5. Create a branch in your forked repository for your changes, ensuring the branch name is meaningful.
|
||||
|
||||
```bash
|
||||
git checkout -b my-docs-branch main
|
||||
```
|
||||
|
||||
6. While making modifications and committing changes, adhere to our [Commit Message Format](#Commit-Message-Format).
|
||||
|
||||
```bash
|
||||
git commit -m "[docs]: xxxx"
|
||||
```
|
||||
|
||||
7. Push your changes to your GitHub repository.
|
||||
|
||||
```bash
|
||||
git push origin my-docs-branch
|
||||
```
|
||||
|
||||
8. Submit a pull request to `Open-Sora-Plan:main` on the GitHub repository page.
|
||||
|
||||
## Commit Message Format
|
||||
|
||||
Commit messages must include both `<type>` and `<summary>` sections.
|
||||
|
||||
```bash
|
||||
[<type>]: <summary>
|
||||
│ │
|
||||
│ └─⫸ Briefly describe your changes, without ending with a period.
|
||||
│
|
||||
└─⫸ Commit Type: |docs|feat|fix|refactor|
|
||||
```
|
||||
|
||||
### Type
|
||||
|
||||
* **docs**: Modify or add documents.
|
||||
* **feat**: Introduce a new feature.
|
||||
* **fix**: Fix a bug.
|
||||
* **refactor**: Restructure code, excluding new features or bug fixes.
|
||||
|
||||
### Summary
|
||||
|
||||
Describe modifications in English, without ending with a period.
|
||||
|
||||
> e.g., git commit -m "[docs]: add a contributing.md file"
|
||||
|
||||
This guideline is borrowed by [minisora](https://github.com/mini-sora/minisora). We sincerely appreciate MiniSora authors for their awesome templates.
|
||||
@@ -0,0 +1,135 @@
|
||||
# 技术报告 v1.0.0
|
||||
|
||||
在2024年3月,我们推出了Open-Sora-Plan,一个旨在复现OpenAI [Sora](https://openai.com/sora)的开源计划。它作为一个基础的开源框架,能够训练视频生成模型包括无条件视频生成,类别引导视频生成,文生视频。
|
||||
|
||||
**今天,我们兴奋地展示Open-Sora-Plan v1.0.0,极大地改进视频生成质量、文本控制能力。**
|
||||
|
||||
相比于之前的视频生成模型,Open-Sora-Plan v1.0.0 有以下的改进:
|
||||
|
||||
1. **CausalVideoVAE高效的训练与推理**。 我们用4×8×8的对视频进行时间和空间的压缩。
|
||||
2. **图片视频联合训练提升视觉质量**。 CasualVideoVAE 将首帧看作图片,天然支持同时编码图片和视频。这允许扩散模型提取更多时空细节来改善质量。
|
||||
|
||||
|
||||
### Open-Source Release
|
||||
我们开源了Open-Sora-Plan去促进视频生成社区的进一步发展。公开代码、数据、模型。
|
||||
- 在线演示:Hugging Face [](https://huggingface.co/spaces/LanguageBind/Open-Sora-Plan-v1.0.0), [](https://replicate.com/camenduru/open-sora-plan-512x512) 和 [](https://colab.research.google.com/github/camenduru/Open-Sora-Plan-jupyter/blob/main/Open_Sora_Plan_jupyter.ipynb), 感谢[@camenduru](https://github.com/camenduru)大力支持我们的工作!🤝
|
||||
- 代码:所有训练脚本和采样代码。
|
||||
- 模型:包括扩散模型和CausalVideoVAE [这里](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.0.0)。
|
||||
- 数据:所有原视频和对应描述 [这里](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.0.0)。
|
||||
|
||||
## 效果
|
||||
|
||||
Open-Sora-Plan v1.0.0支持图片视频联合训练。我们在此展示视频和图片的重建以及生成:
|
||||
|
||||
720×1280**视频重建**。 因为github的限制,原视频放在: [1](https://streamable.com/gqojal), [2](https://streamable.com/6nu3j8).
|
||||
|
||||
https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/88202804/c100bb02-2420-48a3-9d7b-4608a41f14aa
|
||||
|
||||
https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/88202804/8aa8f587-d9f1-4e8b-8a82-d3bf9ba91d68
|
||||
|
||||
1536×1024**图片重建**
|
||||
|
||||
<img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/88202804/1684c3ec-245d-4a60-865c-b8946d788eb9" width="45%"/> <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/88202804/46ef714e-3e5b-492c-aec4-3793cb2260b5" width="45%"/>
|
||||
|
||||
65×1024×1024**文生视频**
|
||||
|
||||
https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/2641a8aa-66ac-4cda-8279-86b2e6a6e011
|
||||
|
||||
65×512×512**文生视频**
|
||||
|
||||
https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/37e3107e-56b3-4b09-8920-fa1d8d144b9e
|
||||
|
||||
|
||||
512×512**文生视频**
|
||||
|
||||

|
||||
|
||||
## 详细技术报告
|
||||
|
||||
### CausalVideoVAE
|
||||
|
||||
#### 模型结构
|
||||
|
||||

|
||||
|
||||
因果VAE架构继承了[Stable-Diffusion Image VAE](https://github.com/CompVis/stable-diffusion/tree/main)。 为了保证图片VAE的预训练权重可以无缝运用到视频VAE中,模型结构采取如下设计:
|
||||
|
||||
1. **CausalConv3D**: 将Conv2D 转变成CausalConv3D可以实现图片和视频的联合训练. CausalConv3D 对第一帧进行特殊处理,因为它无法访问后续帧。对于更多细节,请参考https://github.com/PKU-YuanGroup/Open-Sora-Plan/pull/145
|
||||
|
||||
2. **初始化**:将Conv2D扩展到Conv3D常用的[方法](https://github.com/hassony2/inflated_convnets_pytorch/blob/master/src/inflate.py#L5)有两种:平均初始化和中心初始化。 但我们采用了特定的初始化方法(尾部初始化)。 这种初始化方法确保模型无需任何训练就能够直接重建图像,甚至视频。
|
||||
|
||||
#### 训练细节
|
||||
|
||||
<img width="833" alt="image" src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/88202804/9ffb6dc4-23f6-4274-a066-bbebc7522a14">
|
||||
|
||||
我们展示了 17×256×256 下两种不同初始化方法的损失曲线。黄色曲线代表使用尾部初始化的损失,而蓝色曲线对应中心初始化的损失。 如图所示,尾部初始化在损失曲线上表现出更好的性能。 此外,我们发现中心初始化会导致错误累积,导致长时间内崩溃。
|
||||
|
||||
#### 推理技巧
|
||||
尽管训练Diffusion中VAE始终是冻住的,我们仍然无法负担CasualVideoVAE的花销。在我们的实验中, 80G的显存只能够在半精度下推理一个256×512×512或32×1024×1024的视频 ,这限制了我们扩展到更长更高清的视频。因此我们采用tile convolution,能够以几乎恒定的内存推理任意时长或任意分辨率的视频。
|
||||
|
||||
### 数据构建
|
||||
我们定义高质量的视频数据集包括两个核心法则:(1) 没有与内容无关的水印。(2) 高质量的文本注释。
|
||||
|
||||
**对于法则1**,我们从开源网站(CC0协议)爬取了大约40k videos:1234个来自[mixkit](https://mixkit.co/),7408个来自[pexels](https://www.pexels.com/),31616个来自[pixabay](https://pixabay.com/)。我们根据[Panda70M](https://github.com/snap-research/Panda-70M/blob/main/splitting/README.md)提供的场景变换剪切script将这些视频切成大约434k video clips。事实上,根据我们的剪切结果,从这些网上上爬取的99%的视频都是单一的场景。另外,我们发现爬取的数据中超过60%为风景相关视频。更多细节可以在[这](https://github.com/PKU-YuanGroup/Open-Sora-Dataset)找到。
|
||||
|
||||
**对于法则2**,很难有大量的高质量的文本注释能够从网上直接爬取。因此我们用成熟的图片标注模型来获取高质量的稠密描述。我们对2个多模态大模型进行消融实验:[ShareGPT4V-Captioner-7B](https://github.com/InternLM/InternLM-XComposer/blob/main/projects/ShareGPT4V/README.md) 和 [LLaVA-1.6-34B](https://github.com/haotian-liu/LLaVA)。前者是专门用来制作文本注释的模型,而后者是一个通用的多模态大模型。经过我们的消融实验,他们在caption的表现差不多。然而他们的推理速度在A800上差距很大:40s/it of batch size of 12 for ShareGPT4V-Captioner-7B,15s/it of batch size of 1 for ShareGPT4V-Captioner-7B。我们开源所有的[文本注释和原视频](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.0.0)。
|
||||
|
||||
| 模型名字 | 平均长度 | 最大值 | 标准差 |
|
||||
|---|---|---|---|
|
||||
| ShareGPT4V-Captioner-7B | 170.0827524529121 | 467 | 53.689967539537776 |
|
||||
| LLaVA-1.6-34B | 141.75851073472666 | 472 | 48.52492072346965 |
|
||||
|
||||
### 训练扩散模型
|
||||
与之前的工作类似,我们采用多阶段的级联的训练方法,总共消耗了2048个A800 GPU 小时。我们发现联合图片训练能够显著加速模型的收敛并且增强视觉观感,这与[Latte](https://github.com/Vchitect/Latte)一致。以下是我们的训练花销。
|
||||
|
||||
| 名字 | Stage 1 | Stage 2 | Stage 3 | Stage 4 |
|
||||
|---|---|---|---|---|
|
||||
| 训练视频尺寸 | 17×256×256 | 65×256×256 | 65×512×512 | 65×1024×1024 |
|
||||
| 计算资源 (#A800 GPU x #小时) | 32 × 40 | 32 × 18 | 32 × 6 | 训练中 |
|
||||
| 权重 | [HF](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.0.0/tree/main/17x256x256) | [HF](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.0.0/tree/main/65x256x256) | [HF](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.0.0/tree/main/65x512x512) | 训练中 |
|
||||
| 日志 | [wandb](https://api.wandb.ai/links/linbin/p6n3evym) | [wandb](https://api.wandb.ai/links/linbin/t2g53sew) | [wandb](https://api.wandb.ai/links/linbin/uomr0xzb) | 训练中 |
|
||||
| 训练数据 | ~40k videos | ~40k videos | ~40k videos | ~40k videos |
|
||||
|
||||
## 下版本预览
|
||||
### CausalVideoVAE
|
||||
目前我们发布的CausalVideoVAE v1.0.0版本存在2个主要的缺陷:**运动模糊**以及**网格效应**。我们对CasualVideoVAE做了一系列的改进使它推理成本更低且性能更强大,我们暂时叫它为预览版本,将在下个版本发布。
|
||||
|
||||
**1分钟720×1280视频重建**。 受限于GitHub,我们将原视频放在这:[原视频](https://streamable.com/u4onbb),[重建视频](https://streamable.com/qt8ncc)。
|
||||
|
||||
https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/88202804/cdcfa9a3-4de0-42d4-94c0-0669710e407b
|
||||
|
||||
我们从kinetic 400的验证集中随机选取100个样本进行评估,结果表如下所示:
|
||||
|
||||
| | SSIM↑ | LPIPS↓ | PSNR↑ | FLOLPIPS↓ |
|
||||
|---|---|---|---|---|
|
||||
| v1.0.0 | 0.829 | 0.106 | 27.171 | 0.119 |
|
||||
| Preview | 0.877 | 0.064 | 29.695 | 0.070 |
|
||||
|
||||
#### 运动模糊
|
||||
|
||||
| **v1.0.0** | **预览版本** |
|
||||
| --- | --- |
|
||||
|  |  |
|
||||
|
||||
#### 网格效应
|
||||
|
||||
| **v1.0.0** | **预览版本** |
|
||||
| --- | --- |
|
||||
|  |  |
|
||||
|
||||
### 数据构建
|
||||
|
||||
**数据源**:正如上文提到,我们的数据集中超过60%为风景视频。这意味着我们的开域视频生成能力有限。然而当前的大规模开源数据集大多从YouTube爬取,尽管视频的数量多,但我们担忧视频本身的质量是否达标。因此,我们将继续收集高质量的数据集,同时也欢迎开源社区的推荐。
|
||||
|
||||
**Caption生成流程**:当我们训练时长增加时,我们不得不考虑更有效的视频caption生成方法,而不是多模态图片大模型。我们正在开发一个新的视频注释生成管线,它能够很好的支持长视频,敬请期待。
|
||||
|
||||
### 训练扩散模型
|
||||
尽管目前v1.0.0展现了可喜的结果,但我们仍然离Sora有一段距离。在接下来的工作中,我们主要围绕这三个方面:
|
||||
|
||||
1. **动态分辨率与时长的训练**: 我们的目标是开发出能够以不同分辨率和持续时间训练模型的技术,使训练过程更加灵活、适应性更强。
|
||||
|
||||
2. **更长的视频生成**: 我们将探索扩展模型生成能力的方法,使其能够制作更长的视频,超越目前的限制。
|
||||
|
||||
3. **更多条件控制**: 我们力求增强模型的条件控制能力,为用户提供更多的选项和对生成视频的控制能力。
|
||||
|
||||
另外,通过仔细观察生成的视频,我们发现存在一些不符合常理的斑点或异常的流动,这是由于CasualVideoVAE的性能不足导致的 如上面提到。在未来的实验中,我们将使用更强的VAE,重新训练一个扩散模型。
|
||||
@@ -0,0 +1,136 @@
|
||||
# Report v1.0.0
|
||||
|
||||
In March 2024, we launched a plan called Open-Sora-Plan, which aims to reproduce the OpenAI [Sora](https://openai.com/sora) through an open-source framework. As a foundational open-source framework, it enables training of video generation models, including Unconditioned Video Generation, Class Video Generation, and Text-to-Video Generation.
|
||||
|
||||
**Today, we are thrilled to present Open-Sora-Plan v1.0.0, which significantly enhances video generation quality and text control capabilities.**
|
||||
|
||||
Compared with previous video generation model, Open-Sora-Plan v1.0.0 has several improvements:
|
||||
|
||||
1. **Efficient training and inference with CausalVideoVAE**. We apply a spatial-temporal compression to the videos by 4×8×8.
|
||||
2. **Joint image-video training for better quality**. Our CausalVideoVAE considers the first frame as an image, allowing for the simultaneous encoding of both images and videos in a natural manner. This allows the diffusion model to grasp more spatial-visual details to improve visual quality.
|
||||
|
||||
### Open-Source Release
|
||||
We open-source the Open-Sora-Plan to facilitate future development of Video Generation in the community. Code, data, model are made publicly available.
|
||||
- Demo: Hugging Face demo [](https://huggingface.co/spaces/LanguageBind/Open-Sora-Plan-v1.0.0). 🤝 Enjoying the [](https://replicate.com/camenduru/open-sora-plan-512x512) and [](https://colab.research.google.com/github/camenduru/Open-Sora-Plan-jupyter/blob/main/Open_Sora_Plan_jupyter.ipynb), created by [@camenduru](https://github.com/camenduru), who generously supports our research!
|
||||
- Code: All training scripts and sample scripts.
|
||||
- Model: Both Diffusion Model and CausalVideoVAE [here](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.0.0).
|
||||
- Data: Both raw videos and captions [here](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.0.0).
|
||||
|
||||
## Gallery
|
||||
|
||||
Open-Sora-Plan v1.0.0 supports joint training of images and videos. Here, we present the capabilities of Video/Image Reconstruction and Generation:
|
||||
|
||||
### CausalVideoVAE Reconstruction
|
||||
|
||||
**Video Reconstruction** with 720×1280. Since github can't upload large video, we put it here: [1](https://streamable.com/gqojal), [2](https://streamable.com/6nu3j8).
|
||||
|
||||
https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/88202804/c100bb02-2420-48a3-9d7b-4608a41f14aa
|
||||
|
||||
https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/88202804/8aa8f587-d9f1-4e8b-8a82-d3bf9ba91d68
|
||||
|
||||
**Image Reconstruction** in 1536×1024.
|
||||
|
||||
<img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/88202804/1684c3ec-245d-4a60-865c-b8946d788eb9" width="45%"/> <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/88202804/46ef714e-3e5b-492c-aec4-3793cb2260b5" width="45%"/>
|
||||
|
||||
**Text-to-Video Generation** with 65×1024×1024
|
||||
|
||||
https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/2641a8aa-66ac-4cda-8279-86b2e6a6e011
|
||||
|
||||
**Text-to-Video Generation** with 65×512×512
|
||||
|
||||
https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/37e3107e-56b3-4b09-8920-fa1d8d144b9e
|
||||
|
||||
|
||||
**Text-to-Image Generation** with 512×512
|
||||
|
||||

|
||||
|
||||
## Detailed Technical Report
|
||||
|
||||
### CausalVideoVAE
|
||||
|
||||
#### Model Structure
|
||||
|
||||

|
||||
|
||||
The CausalVideoVAE architecture inherits from the [Stable-Diffusion Image VAE](https://github.com/CompVis/stable-diffusion/tree/main). To ensure that the pretrained weights of the Image VAE can be seamlessly applied to the Video VAE, the model structure has been designed as follows:
|
||||
|
||||
1. **CausalConv3D**: Converting Conv2D to CausalConv3D enables joint training of image and video data. CausalConv3D applies a special treatment to the first frame, as it does not have access to subsequent frames. For more specific details, please refer to https://github.com/PKU-YuanGroup/Open-Sora-Plan/pull/145
|
||||
|
||||
2. **Initialization**: There are two common [methods](https://github.com/hassony2/inflated_convnets_pytorch/blob/master/src/inflate.py#L5) to expand Conv2D to Conv3D: average initialization and center initialization. But we employ a specific initialization method (tail initialization). This initialization method ensures that without any training, the model is capable of directly reconstructing images, and even videos.
|
||||
|
||||
#### Training Details
|
||||
|
||||
<img width="833" alt="image" src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/88202804/9ffb6dc4-23f6-4274-a066-bbebc7522a14">
|
||||
|
||||
We present the loss curves for two distinct initialization methods under 17×256×256. The yellow curve represents the loss using tail init, while the blue curve corresponds to the loss from center initialization. As shown in the graph, tail initialization demonstrates better performance on the loss curve. Additionally, we found that center initialization leads to error accumulation, causing the collapse over extended durations.
|
||||
|
||||
#### Inference Tricks
|
||||
Despite the VAE in Diffusion training being frozen, we still find it challenging to afford the cost of the CausalVideoVAE. In our case, with 80GB of GPU memory, we can only infer a video of either 256×512×512 or 32×1024×1024 resolution using half-precision, which limits our ability to scale up to longer and higher-resolution videos. Therefore, we adopt tile convolution, which allows us to infer videos of arbitrary duration or resolution with nearly constant memory usage.
|
||||
|
||||
### Data Construction
|
||||
We define a high-quality video dataset based on two core principles: (1) No content-unrelated watermarks. (2) High-quality and dense captions.
|
||||
|
||||
**For principles 1**, we crawled approximately 40,000 videos from open-source websites under the CC0 license. Specifically, we obtained 1,234 videos from [mixkit](https://mixkit.co/), 7,408 videos from [pexels](https://www.pexels.com/), and 31,616 videos from [pixabay](https://pixabay.com/). These videos adhere to the principle of having no content-unrelated watermarks. According to the scene transformation and clipping script provided by [Panda70M](https://github.com/snap-research/Panda-70M/blob/main/splitting/README.md), we have divided these videos into approximately 434,000 video clips. In fact, based on our clipping results, 99% of the videos obtained from these online sources are found to contain single scenes. Additionally, we have observed that over 60% of the crawled data comprises landscape videos. More details can be found [here](https://github.com/PKU-YuanGroup/Open-Sora-Dataset).
|
||||
|
||||
**For principles 2**, it is challenging to directly crawl a large quantity of high-quality dense captions from the internet. Therefore, we utilize a mature Image-captioner model to obtain high-quality dense captions. We conducted ablation experiments on two multimodal large models: [ShareGPT4V-Captioner-7B](https://github.com/InternLM/InternLM-XComposer/blob/main/projects/ShareGPT4V/README.md) and [LLaVA-1.6-34B](https://github.com/haotian-liu/LLaVA). The former is specifically designed for caption generation, while the latter is a general-purpose multimodal large model. After conducting our ablation experiments, we found that they are comparable in performance. However, there is a significant difference in their inference speed on the A800 GPU: 40s/it of batch size of 12 for ShareGPT4V-Captioner-7B, 15s/it of batch size of 1 for LLaVA-1.6-34B. We open-source all annotations [here](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.0.0). We show some statistics here, and we set the maximum length of the model to 300, which covers almost 99% of the samples.
|
||||
|
||||
| Name | Avg length | Max | Std |
|
||||
|---|---|---|---|
|
||||
| ShareGPT4V-Captioner-7B | 170.0827524529121 | 467 | 53.689967539537776 |
|
||||
| LLaVA-1.6-34B | 141.75851073472666 | 472 | 48.52492072346965 |
|
||||
|
||||
### Training Diffusion Model
|
||||
Similar to previous work, we employ a multi-stage cascaded training approach, which consumes a total of 2,528 A800 GPU hours. We found that joint training with images significantly accelerates model convergence and enhances visual perception, aligning with the findings of [Latte](https://github.com/Vchitect/Latte). Below is our training card:
|
||||
|
||||
| Name | Stage 1 | Stage 2 | Stage 3 | Stage 4 |
|
||||
|---|---|---|---|---|
|
||||
| Training Video Size | 17×256×256 | 65×256×256 | 65×512×512 | 65×1024×1024 |
|
||||
| Compute (#A800 GPU x #Hours) | 32 × 40 | 32 × 22 | 32 × 17 | Under training |
|
||||
| Checkpoint | [HF](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.0.0/tree/main/17x256x256) | [HF](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.0.0/tree/main/65x256x256) | [HF](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.0.0/tree/main/65x512x512) | Under training |
|
||||
| Log | [wandb](https://api.wandb.ai/links/linbin/p6n3evym) | [wandb](https://api.wandb.ai/links/linbin/t2g53sew) | [wandb](https://api.wandb.ai/links/linbin/uomr0xzb) | Under training |
|
||||
| Training Data | ~40k videos | ~40k videos | ~40k videos | ~40k videos |
|
||||
|
||||
## Next Release Preview
|
||||
### CausalVideoVAE
|
||||
Currently, the released version of CausalVideoVAE (v1.0.0) has two main drawbacks: **motion blurring** and **gridding effect**. We have made a series of improvements to CausalVideoVAE to reduce its inference cost and enhance its performance. We are currently referring to this enhanced version as the "preview version," which will be released in the next update. Preview reconstruction is as follows:
|
||||
|
||||
**1 min Video Reconstruction with 720×1280**. Since github can't put too big video, we put it here: [origin video](https://streamable.com/u4onbb), [reconstruction video](https://streamable.com/qt8ncc).
|
||||
|
||||
https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/88202804/cdcfa9a3-4de0-42d4-94c0-0669710e407b
|
||||
|
||||
We randomly selected 100 samples from the validation set of Kinetics-400 for evaluation, and the results are presented in the following table:
|
||||
|
||||
| | SSIM↑ | LPIPS↓ | PSNR↑ | FLOLPIPS↓ |
|
||||
|---|---|---|---|---|
|
||||
| v1.0.0 | 0.829 | 0.106 | 27.171 | 0.119 |
|
||||
| Preview | 0.877 | 0.064 | 29.695 | 0.070 |
|
||||
|
||||
#### Motion Blurring
|
||||
|
||||
| **v1.0.0** | **Preview** |
|
||||
| --- | --- |
|
||||
|  |  |
|
||||
|
||||
#### Gridding effect
|
||||
|
||||
| **v1.0.0** | **Preview** |
|
||||
| --- | --- |
|
||||
|  |  |
|
||||
|
||||
### Data Construction
|
||||
|
||||
**Data source**. As mentioned earlier, over 60% of our dataset consists of landscape videos. This implies that our ability to generate videos in other domains is limited. However, most of the current large-scale open-source datasets are primarily obtained through web scraping from platforms like YouTube. While these datasets provide a vast quantity of videos, we have concerns about the quality of the videos themselves. Therefore, we will continue to collect high-quality datasets and also welcome recommendations from the open-source community. We are launching an Open-Sora-Dataset project, check out the details at [Open-Sora-Dataset](https://github.com/PKU-YuanGroup/Open-Sora-Dataset)
|
||||
|
||||
**Caption Generation Pipeline**. As the video duration increases, we need to consider more efficient methods for video caption generation instead of relying solely on large multimodal image models. We are currently developing a new video caption generation pipeline that provides robust support for long videos. We are excited to share more details with you in the near future. Stay tuned!
|
||||
|
||||
### Training Diffusion Model
|
||||
Although v1.0.0 has shown promising results, we acknowledge that we still have a ways to go to reach the level of Sora. In our upcoming work, we will primarily focus on three aspects:
|
||||
|
||||
1. **Training support for dynamic resolution and duration**: We aim to develop techniques that enable training models with varying resolutions and durations, allowing for more flexible and adaptable training processes.
|
||||
|
||||
2. **Support for longer video generation**: We will explore methods to extend the generation capabilities of our models, enabling them to produce longer videos beyond the current limitations.
|
||||
|
||||
3. **Enhanced conditional control**: We seek to enhance the conditional control capabilities of our models, providing users with more options and control over the generated videos.
|
||||
|
||||
Furthermore, through careful observation of the generated videos, we have noticed the presence of some non-physiological speckles or abnormal flow. This can be attributed to the limited performance of CausalVideoVAE, as mentioned earlier. In future experiments, we plan to retrain a diffusion model using a more powerful version of CausalVideoVAE to address these issues.
|
||||
@@ -0,0 +1,256 @@
|
||||
# Report v1.1.0
|
||||
|
||||
In April 2024, we launched Open-Sora-Plan v1.0.0, featuring a simple and efficient design along with remarkable performance in text-to-video generation. It has already been adopted as a foundational model in numerous research projects, including its data and model.
|
||||
|
||||
**Today, we are excited to present Open-Sora-Plan v1.1.0, which significantly improves video generation quality and duration.**
|
||||
|
||||
Compared to the previous version, Open-Sora-Plan v1.1.0, the improvements include:
|
||||
|
||||
1. **Better compressed visual representations**. We optimized the CausalVideoVAE architecture, which now has stronger performance and higher inference efficiency.
|
||||
2. **Generate higher quality, longer videos**. We used higher quality visual data and captions by [ShareGPT4Video](https://sharegpt4video.github.io/), enabling the model to better understand the workings of the world.
|
||||
|
||||
Along with performance improvements, Open-Sora-Plan v1.1.0 maintains the minimalist design and data efficiency of v1.0.0. Remarkably, we found that v1.1.0 exhibits similar performance to the Sora base model, indicating that our version's evolution aligns with the scaling law demonstrated by Sora.
|
||||
|
||||
### Open-Source Release
|
||||
We open-source the Open-Sora-Plan to facilitate future development of Video Generation in the community. Code, data, model will be made publicly available.
|
||||
- Demo: Hugging Face demo [here](https://huggingface.co/spaces/LanguageBind/Open-Sora-Plan-v1.1.0).
|
||||
- Code: All training scripts and sample scripts.
|
||||
- Model: Both Diffusion Model and CasualVideoVAE [here](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.1.0).
|
||||
- Data: Both raw videos and captions [here](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.1.0).
|
||||
|
||||
## Gallery
|
||||
|
||||
|
||||
### 221×512×512 Text-to-Video Generation
|
||||
|
||||
| 221×512×512 (9.2s) | 221×512×512 (9.2s) | 221×512×512 (9.2s) | 221×512×512 (9.2s) |
|
||||
| --- | --- | --- | --- |
|
||||
| <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/6d18f344-f7da-44eb-9e07-77813f6b5e90" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/71f75e72-e9ee-4ce7-b8ea-d2d45a6f367e" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/80430eae-a3b4-4f24-b448-0db2919327d6" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/dc217894-a8c8-4174-a42c-acd2811f61f5" width=224> |
|
||||
| This close-up shot of a Victoria crowned pigeon showcases its striking blue plumage ... | a cat wearing sunglasses and working as a lifeguard at pool. | Photorealistic closeup video of two pirate ships battling each other as they sail ... | A movie trailer featuring the adventures ofthe 30 year old spacemanwearing a redwool ... |
|
||||
| <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/f9c5823f-aa03-40ee-8335-684684f5c842" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/f207d798-8988-45b0-b836-347e499ee000" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/d40c38dc-9f26-4591-8163-c7089e1553e3" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/67b40ce1-135d-4ae2-a1ee-5a0866461eb2" width=224> |
|
||||
| A snowy forest landscape with a dirt road running through it. The road is flanked by ... | Drone shot along the Hawaii jungle coastline, sunny day. Kayaks in the water. | Alpacas wearing knit wool sweaters, graffiti background, sunglasses. | The camera rotates around a large stack of vintage televisions all showing different ... |
|
||||
| <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/42542b4e-b1b8-49b8-ada4-7bcfde8e1453" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/4eee2619-a5ca-4a32-b350-e65d6220c8f7" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/e6152c93-4edf-4569-8d17-1effd87a7780" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/ec78d855-07c7-4421-896a-3c46a83ec129" width=224> |
|
||||
| A drone camera circles around a beautiful historic church built on a rocky outcropping ... | Aerial view of Santorini during the blue hour, showcasing the stunning architecture ... | A robot dog explores the surface of Mars, kicking up red dust as it investigates ... | An aerial shot of a lighthouse standing tall on a rocky cliff, its beacon cutting ... |
|
||||
| <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/98897215-eae9-49f3-8fdb-df1d4b74d435" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/10e0f93d-925f-4b38-8205-7d89f49195f1" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/5453cf37-29ac-423d-9fb2-05f23416ca3e" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/77928824-6705-4d83-a7b4-43fdb74790bf" width=224> |
|
||||
| 3D animation of a small, round, fluffy creature with big, expressive eyes explores ... | A corgi vlogging itself in tropical Maui. | A single drop of liquid metal falls from a floating orb, landing on a mirror-like ... | The video presents an abstract composition centered around a hexagonal shape adorned ... |
|
||||
|
||||
### 65×512×512 Text-to-Video Generation
|
||||
|
||||
| 65×512×512 (2.7s) | 65×512×512 (2.7s) | 65×512×512 (2.7s) | 65×512×512 (2.7s) |
|
||||
| --- | --- | --- | --- |
|
||||
| <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/a0601f20-579c-4e2e-832c-5763546718cc" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/55229eca-de3a-476b-930b-13a35eb5db30" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/74b9e7a1-0fa4-4f0d-8faf-0c84d97b11b5" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/66b06822-2652-453e-80fb-dd2988b730ce" width=224> |
|
||||
| Extreme close-up of chicken and green pepper kebabs grilling on a barbeque with flames. | 3D animation of a small, round, fluffy creature with big, expressive eyes explores a ... | A corgi vlogging itself in tropical Maui. | In a studio, there is a painting depicting a ship sailing through the rough sea. |
|
||||
| <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/4d27ff13-e725-4602-bf17-90df2c0d8005" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/049fd4db-f2fe-4633-ab62-1dda8268e090" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/aba01259-60f2-49ef-aa33-e738dc8c9a49" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/98178397-61b0-4200-9ab9-9bef2728ed98" width=224> |
|
||||
| A robot dog trots down a deserted alley at night, its metallic paws clinking softly ... | A solitary spider weaves its web in a quiet corner. The web shimmers and glows with ... | A lone surfer rides a massive wave, skillfully maneuvering through the surf. The water ... | A solitary cheetah sprints across the savannah, its powerful muscles propelling it ... |
|
||||
| <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/3964dfcd-d1b4-406b-916c-d4a702184a27" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/2a5fd1c0-9304-46e4-af35-5ffcc718bf08" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/73e1304a-6241-4e19-9dde-f2b1032edefd" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/c82b822b-cadd-4f11-bcc3-29e3651c02c0" width=224> |
|
||||
| A solitary astronaut plants a flag on an alien planet covered in crystal formations ... | At dawn's first light, a spaceship slowly exits the edge of the galaxy against a ...| A dapper puppy in a miniature suit, basking in the afternoon sun, adjusting his tie ... | A wise old elephant painting abstract art with its trunk, each stroke a burst of color ... |
|
||||
| <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/8edfa249-272c-4773-8728-12686527771e" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/33338d8e-5ea7-4b57-9e94-97f3ee404033" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/227fa6b6-801b-438b-9b30-cd3a4e0a7f2f" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/b5d5ebee-ab13-4e32-8b79-e6cb8f08d4a0" width=224> |
|
||||
| In an ornate, historical hall, a massive tidal wave peaks and begins to crash. Two ... | A Shiba Inu dog wearing a beret and black turtleneck. | A painting of a boat on water comes to life, with waves crashing and the boat becoming ... | Many spotted jellyfish pulsating under water. Their bodies are transparent and glowing ... |
|
||||
| <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/fe8e9450-5a80-435d-b050-6b2fe11cdf53" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/7d9335df-817d-479d-9ea7-615cb50c66b8" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/34c1dda6-e420-4edd-bbcd-38ff8e542ec6" width=224> | |
|
||||
| An animated hedgehog with distinctive spiky hair and large eyes is seen exploring a ... | An animated rabbit in a playful pink snowboarding outfit is carving its way down a ... | A person clad in a space suit with a helmet and equipped with a chest light and arm ... | |
|
||||
|
||||
### 65×512×512 Video Editing
|
||||
|
||||
| generated 65×512×512 (2.7s) | edited 65×512×512 (2.7s) |
|
||||
| --- | --- |
|
||||
| <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/edb8e8c2-5eef-4c90-85fb-6adb035067c3" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/32d93845-8904-4f8f-832e-37eba2ceb542" width=224> |
|
||||
| <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/a70d0d91-0d61-4aa4-9520-6e4a6c477f12" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/7913e06f-1e0b-4d06-8233-72c882c6abfe" width=224> |
|
||||
| <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/0e614ec0-fba0-4f42-a343-d4607966dd40" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/c531d930-410c-4614-890d-bae8013f33c2" width=224> |
|
||||
|
||||
### 512×512 Text-to-Image Generation
|
||||
|
||||
<img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/e44b7f8a-5da2-49c2-87c4-52ea680ad43b" width=512>
|
||||
|
||||
## Detailed Technical Report
|
||||
|
||||
### CasualVideoVAE
|
||||
|
||||
#### Model Structure
|
||||
|
||||
As the number of frames increases, the encoder overhead of CausalVideoVAE gradually rises. When training with 257 frames, 80GB of VRAM is insufficient for the VAE to encode the video. Therefore, we reduced the number of CausalConv3D layers, retaining only the last two stages of CausalConv3D in the encoder. This change significantly lowers the overhead while maintaining nearly the same performance. Note that we only modified the encoder; the decoder still retains all CausalConv3D layers, as training the Diffusion Model does not require the decoder.
|
||||
|
||||
<img width="722" alt="vaemodel" src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/b6f8a638-cfb2-40f3-94be-45af8dbad18e">
|
||||
|
||||
We compare the computational overhead of the two versions by testing the forward inference of the encoder on the H100.
|
||||
|
||||
| Version | 129×256×256 | | 257×256×256 | | 513×256×256 | |
|
||||
|---|---|---|---|---|---|---|
|
||||
| | Peak Mem. | Speed | Peak Mem. | Speed |Peak Mem. | Speed |
|
||||
| v1.0.0 | 22G | 2.9 it/s | OOM | - | OOM | - |
|
||||
| v1.1.0 | 18G | 4.9 it/s | 34G | 2.5 it/s | 61G | 1.2 it/s |
|
||||
|
||||
|
||||
#### Temporal Module
|
||||
|
||||
<img width="480" alt="vaemodel" src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/7c8a4263-b7d1-4edc-a60c-801ae9b4344f">
|
||||
|
||||
In v1.0.0, our temporal module had only TemporalAvgPool. TemporalAvgPool leads to the loss of high-frequency information in the video, such as details and edges. To address this issue, we improved this module in v1.1.0. As shown in the figure below, we introduced convolution and added learnable weights, allowing different branches to decouple different features. When we omit CausalConv3D, the video is reconstructed very blurry. Similarly, when we omit TemporalAvgPool, the video becomes very sharp.
|
||||
|
||||
| | SSIM↑ | LPIPS↓ | PSNR↑ |
|
||||
|---|---|---|---|
|
||||
| Base | 0.850 | 0.091 | 28.047 |
|
||||
| + Frames | 0.868 | 0.070 | 28.829 |
|
||||
| + Reset mixed factor | 0.873 | 0.070 | 29.140 |
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
#### Training Details
|
||||
|
||||
Similar to v1.0.0, we initialized from the Latent Diffusion's VAE and used tail initialization. For CausalVideoVAE, we trained for 100k steps in the first stage with a video shape of 9×256×256. Subsequently, we increased the frame count from 9 to 25 and found that this significantly improved the model's performance. It is important to clarify that we enabled the mixed factor during both the first and second stages, with a value of a (sigmoid(mixed factor)) reaching 0.88 at the end of training, indicating the model's tendency to retain low-frequency information. In the third stage, we reinitialized the mixed factor to 0.5 (sigmoid(0.5) = 0.6225), which further enhanced the model's capabilities.
|
||||
|
||||
#### Loss Function
|
||||
|
||||
We found that using GAN loss helps retain high-frequency information and alleviates grid artifacts. Additionally, we observed that switching from 2D GAN to 3D GAN provides further improvements.
|
||||
|
||||
| GAN Loss/Step | SSIM↑ | LPIPS↓ | PSNR↑ |
|
||||
|---|---|---|---|
|
||||
| 2D/80k | 0.879 | 0.068 | 29.480 |
|
||||
| 3D/80k | 0.882 | 0.067 | 29.890 |
|
||||
|
||||
#### Inference Tricks
|
||||
Therefore, we introduced a method called **temporal rollback tiled convolution**, a tiling approach specifically designed for CausalVideoVAE. Specifically, all windows except the first one discard the first frame because the first frame in a window is treated as an image, while the remaining frames should be treated as video frames.
|
||||
|
||||
<img width="633" alt="tiled_temp" src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/0a06011e-1d6c-410a-9f1c-82c4122a018a">
|
||||
|
||||
We tested the speed on the H100 with a window size of 65×256×256.
|
||||
|
||||
| Version | 129×256×256 | | 257×256×256 | | 513×256×256 | |
|
||||
|---|---|---|---|---|---|---|
|
||||
| | Peak Mem. | Speed | Peak Mem. | Speed |Peak Mem. | Speed |
|
||||
| 4×8×8 | 10G | 1.3 s/it | 10G | 2.6 s/it | 10G | 5.3 s/it |
|
||||
|
||||
### Data Construction
|
||||
Since Open-Sora-Plan supports joint training of images and videos, our data collection is divided into two parts: images and videos. Images do not need to originate from videos; they are independent datasets. We spent approximately 32×240 H100 hours generating image and video captions, and all of this is **open source**!
|
||||
|
||||
#### Image-Text Collection Pipeline
|
||||
We obtained 11 million image-text pairs from [Pixart-Alpha](https://huggingface.co/datasets/PixArt-alpha/SAM-LLaVA-Captions10M), with captions generated by [LLaVA](https://github.com/haotian-liu/LLaVA). Additionally, we utilized the high-quality OCR dataset [Anytext-3M](https://github.com/tyxsspa/AnyText), which pairs each image with corresponding OCR characters. However, these captions were insufficient to describe the entire image, so we used [InternVL-1.5](https://github.com/OpenGVLab/InternVL) for supplementary descriptions. Since T5 only supports English, we filtered for English data, which constitutes about half of the complete dataset. Furthermore, we selected high-quality images from [Laion-5B](https://laion.ai/blog/laion-5b/) to enhance human-like generation quality. The selection criteria included high resolution, high aesthetic scores, and watermark-free images containing people.
|
||||
|
||||
Here, we are open-sourcing the prompt used for InternVL-1.5:
|
||||
```
|
||||
# for anytext-3m
|
||||
Combine this rough caption: "{}", analyze the image in a comprehensive and detailed manner. "{}" can be recognized in the image.
|
||||
# for human-160k
|
||||
Analyze the image in a comprehensive and detailed manner.
|
||||
```
|
||||
|
||||
| Name | Image Source | Text Captioner | Num pair |
|
||||
|---|---|---|---|
|
||||
| SAM-11M | [SAM](https://ai.meta.com/datasets/segment-anything/) | [LLaVA](https://github.com/haotian-liu/LLaVA) | 11,185,255 |
|
||||
| Anytext-3M-en | [Anytext](https://github.com/tyxsspa/AnyText) | [InternVL-1.5](https://github.com/OpenGVLab/InternVL) | 1,886,137 |
|
||||
| Human-160k | [Laion](https://laion.ai/blog/laion-5b/) | [InternVL-1.5](https://github.com/OpenGVLab/InternVL) | 162,094 |
|
||||
|
||||
|
||||
#### Video-Text Collection Pipeline
|
||||
In v1.0.0, we sampled one frame from each video to generate captions. However, as video length increased, a single frame could not adequately describe the entire video's content or temporal movements. Therefore, we used a video captioner to generate captions for the entire video clip. Specifically, we used [ShareGPT4Video](https://sharegpt4video.github.io/), which effectively covers temporal information and describes the entire video content. The v1.1.0 video dataset comprises approximately 3k hours, compared to only 300 hours in v1.0.0. As before, we have open-sourced all text annotations and videos (both under the CC0 license), which can be found [here](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.1.0/tree/main).
|
||||
|
||||
|
||||
|
||||
| Name | Hours | Num frames | Num pair |
|
||||
|---|---|---|---|
|
||||
| [Mixkit](https://mixkit.co/) | 42.0h | 65 | 54,735 |
|
||||
| | | 513 | 1,997 |
|
||||
| [Pixabay](https://pixabay.com/) | 353.3h | 65 | 601,513 |
|
||||
| | | 513 | 51,483 |
|
||||
| [Pexel](https://www.pexels.com/) | 2561.9h | 65 | 3,832,666 |
|
||||
| | | 513 | 271,782 |
|
||||
|
||||
### Training Diffusion Model
|
||||
Similar to our previous work, we employed a multi-stage cascaded training method. Below is our training card:
|
||||
|
||||
#### Stage 1
|
||||
|
||||
Surprisingly, we initially believed that the performance of the diffusion model would improve with longer training. However, by observing the [logs](https://api.wandb.ai/links/linbin/o76j03j4), we found that videos generated at 50k steps were of higher quality than those at 70-100k steps. In fact, extensive sampling revealed that checkpoints at 40-60k steps outperformed those at 80-100k steps. Quantitatively, 50k steps correspond to approximately 2 epochs of training. It is currently unclear whether this is due to overfitting from a small dataset or the limited capacity of the 2+1D model.
|
||||
|
||||
#### Stage 2
|
||||
|
||||
In the second stage, we used Huawei Ascend computing power for training. This stage's training and inference were fully supported by Huawei. We conducted sequence parallel training and inference on a large-scale cluster, distributing one sample across eight ranks. Models trained on Huawei Ascend can also be loaded into GPUs and generate videos of the same quality.
|
||||
|
||||
|
||||
#### Stage 3
|
||||
|
||||
In the third stage, we further increased the frame count to 513 frames, approximately 21 seconds at 24 FPS. However, this stage presents several challenges, such as ensuring temporal consistency in the 2+1D model over long durations and whether the current amount of data is sufficient. We are still training the model for this stage and continuously monitoring its progress.
|
||||
|
||||
| Name | Stage 1 | Stage 2 | Stage 3 |
|
||||
|---|---|---|---|
|
||||
| Training Video Size | 65×512×512 | 221×512×512 | 513×512×512 |
|
||||
| Compute (#Num x #Hours) | 80 H100 × 72 | 512 Ascend × 72 | Under Training |
|
||||
| Checkpoint | [HF](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.1.0/tree/main/65x512x512) | [HF](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.1.0/tree/main/221x512x512) | Under Training |
|
||||
| Log | [wandb](https://api.wandb.ai/links/linbin/o76j03j4) | - | - |
|
||||
| Training Data | ~3k hours videos + 13M images | | |
|
||||
|
||||
### Video Editing
|
||||
|
||||
The recently proposed [ReVideo](https://mc-e.github.io/project/ReVideo/) achieves accurate video editing by modifying the first frame and applying motion control within the edited area. Although it achieves excellent video editing performance, the editing length is limited by the base model [SVD](https://github.com/Stability-AI/generative-models). Open-Sora, as a fundamental model for long-video generation, can compensate for this issue. Currently, we are collaborating with the ReVideo team to use Open-Sora as the base model for long video editing. Some preliminary results are shown [here]().
|
||||
|
||||
The initial version still needs improvement in several aspects. In the future, we will continue to explore integration with ReVideo to develop improved long-video editing models.
|
||||
|
||||
## Failed Case and Discussion
|
||||
|
||||
Despite the promising results of v1.1.0, there remains a gap between our model and Sora. Here, we present some failure cases and discuss them.
|
||||
|
||||
### CasualVideoVAE
|
||||
|
||||
Despite the significant performance improvement of VAE in v1.1.0 over v1.0.0, we still encounter failures in challenging cases, such as sand dunes and leaves. The video on the left shows the reconstructed video downsampled by a factor of 4 in time, while the video on the right is downsampled by a factor of 2. Both exhibit jitter when reconstructing fine-grained features. This indicates that reducing temporal downsampling alone cannot fully resolve the jitter issue.
|
||||
|
||||
https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/1a87d6d8-4bf1-4b4e-83bb-84870c5c3a11
|
||||
|
||||
https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/1a87d6d8-4bf1-4b4e-83bb-84870c5c3a11
|
||||
|
||||
### Diffusion Model
|
||||
|
||||
#### Semantic distortion
|
||||
|
||||
On the left is a video generated by v1.1.0 showing a puppy in the snow. In this video, the puppy's head exhibits semantic distortion, indicating that the model struggles to correctly identify which head belongs to which dog. On the right is a video generated by Sora's [base model](https://openai.com/index/video-generation-models-as-world-simulators/). We observe that Sora's early base model also experienced semantic distortion issues. This suggests that we may achieve better results by scaling up the model and increasing the amount of training data.
|
||||
|
||||
Prompt:A litter of golden retriever puppies playing in the snow.Their heads pop out of the snow, covered in.
|
||||
|
||||
| Our | Sora Base×1 | Sora Base×4 | Sora Base×32 |
|
||||
|---|---|---|---|
|
||||
| <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/1d456168-afad-4e22-ae3b-fc28eca935e8" width=224> |<img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/c4ca99d9-9492-45c8-a75e-6efe21c330aa" width=224> |<img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/b7b52894-f58b-4e64-858b-015247108b8b" width=224> | <img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/dcaf793b-1da4-4cc1-9c17-8a46d55e80e6" width=224> |
|
||||
|
||||
#### Limited dynamics
|
||||
|
||||
The primary difference between videos and images lies in their dynamic nature, where objects undergo a series of changes across consecutive frames. However, the videos generated by v1.1.0 still contain many instances of limited dynamics. Upon reviewing a large number of training videos, we found that while web-crawled videos have high visual quality, they are often filled with meaningless close-up shots. These close-ups typically show minimal movement or are even static. On the left, we present a generated video of a bird, while on the right is a training video we found, which is almost static. There are many similar videos in the dataset from stock footage sites.
|
||||
|
||||
Prompt:This close-up shot of a Victoria crowned pigeon showcases its striking blue plumage and red chest. Its crest is made of delicate, lacy feathers, while its eye is a striking red color. The bird's head is tilted slightly to the side,giving the impression of it looking regal and majestic. The background is blurred,drawing attention to the bird's striking appearance.
|
||||
|
||||
|
||||
| Our | Raw video |
|
||||
|---|---|
|
||||
|<img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/7ffb6bc6-b52c-488e-9f29-d7d90bda44d6" width=224> |<img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/95fbbca4-e206-42f6-8c6b-af1063c442c6" width=224> |
|
||||
|
||||
#### Negative prompt
|
||||
|
||||
We found that using negative prompts can significantly improve video quality, even though we did not explicitly tag the training data with different labels. On the left is a video sampled using a negative prompt, while on the right is a video generated without a negative prompt. This suggests that we may need to incorporate more prior knowledge into the training data. For example, when a video has a watermark, we should note "watermark" in the corresponding caption. When a video's bitrate is too low, we should add more tags to distinguish it from high-quality videos, such as "low quality" or "blurry." We believe that explicitly injecting these priors can help the model differentiate between the vast amounts of pretraining data (low quality) and the smaller amounts of fine-tuning data (high quality), thereby generating higher quality videos.
|
||||
|
||||
Prompt:A litter of golden retriever puppies playing in the snow.Their heads pop out of the snow, covered in.
|
||||
Negative Prompt:distorted, discontinuous, ugly, blurry, low resolution, motionless, static, low quality
|
||||
|
||||
|
||||
| With Negative Prompt | Without Negative Prompt |
|
||||
|---|---|
|
||||
|<img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/1d456168-afad-4e22-ae3b-fc28eca935e8" width=224> |<img src="https://github.com/PKU-YuanGroup/Open-Sora-Plan/assets/62638829/7ad17f96-bfab-455a-830d-0daebccaf6fb" width=224> |
|
||||
|
||||
## Future Work
|
||||
|
||||
In our future work, we will focus on two main areas: (1) data scaling and (2) model design. Once we have a robust baseline model, we will extend it to handle variable durations and conditional control models.
|
||||
|
||||
### Data Scaling
|
||||
|
||||
#### Data source
|
||||
|
||||
As mentioned earlier, our dataset is entirely sourced from stock footage websites. Although these videos are of high quality, many consist of close-up shots of specific areas, resulting in slow motion in the videos. We believe this is one of the main reasons for the limited dynamics observed. Therefore, we will continue to collect datasets from diverse sources to address this issue.
|
||||
|
||||
#### Data volume
|
||||
|
||||
In v1.1.0, our dataset comprises only ~3k hours of video. We are actively collecting more data and anticipate that the video dataset for the next version will reach ~100k hours. We welcome recommendations from the open-source community for additional datasets.
|
||||
|
||||
### Model Design
|
||||
|
||||
#### CasualVideoVAE
|
||||
In our internal testing, even without downsampling in time, we found that it is not possible to completely resolve the jitter issue in reconstructing fine-grained features. Therefore, we need to reconsider how to mitigate video jitter to the greatest extent possible while simultaneously supporting both images and videos. We will introduce a more powerful CasualVideoVAE in the next version.
|
||||
|
||||
#### Diffusion Model
|
||||
In v1.1.0, we found that 2+1D models can generate higher-quality videos in short durations. However, for long videos, they tend to exhibit discontinuities and inconsistencies. Therefore, we will explore more possibilities in model architecture to address this issue.
|
||||
@@ -0,0 +1,193 @@
|
||||
# Report v1.2.0
|
||||
|
||||
In May 2024, we launched Open-Sora-Plan v1.1.0, featuring a 2+1D model architecture that could be quickly utilized for exploratory training in text-to-video generation tasks. However, when handling dense visual tokens, the 2+1D architecture could not simultaneously process spatial and temporal dimensions. Therefore, we transitioned to **a 3D full attention architecture**, which better captures the joint spatial-temporal features. Although this version is experimental, it advances video generation architecture to a new realm, leading us to release it as v1.2.0.
|
||||
|
||||
Compared to previous video generation models, Open-Sora-Plan v1.2.0 offers the following improvements:
|
||||
|
||||
1. **Better compressed visual representations**. We optimized the structure of CausalVideoVAE, which now delivers enhanced performance and higher inference efficiency.
|
||||
2. **Better video generation architecture**. Instead of 2+1D, we use a diffusion model with a 3D full attention architecture, which provides a better understanding of the world.
|
||||
|
||||
|
||||
### Open-Source Release
|
||||
We open-source the Open-Sora-Plan to facilitate future development of Video Generation in the community. Code, data, model are made publicly available.
|
||||
- Code: All training scripts and sample scripts.
|
||||
- Model: Both Diffusion Model and CasualVideoVAE [here](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.2.0).
|
||||
- Data: Filtered data [here](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.2.0).
|
||||
|
||||
## Gallery
|
||||
|
||||
93×1280×720 Text-to-Video Generation. The video quality has been compressed for playback on GitHub.
|
||||
|
||||
<table class="center">
|
||||
<tr>
|
||||
<td><video src="https://github.com/user-attachments/assets/1c84bc92-d585-46c9-ae7c-e5f79cefea88" autoplay></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
## Detailed Technical Report
|
||||
|
||||
### CausalVideoVAE
|
||||
|
||||
#### Model Structure
|
||||
|
||||
The VAE in version 1.2.0 maintains the overall architecture of the previous version but merges the temporal and spatial downsampling layers. In version 1.1.0, we performed spatial downsampling (stride=1,2,2) followed by temporal downsampling (stride=2,1,1). In version 1.2.0, we conduct both spatial and temporal downsampling simultaneously (stride=2,2,2) and perform spatial-temporal upsampling in the decoder (interpolate_factor=2,2,2).
|
||||
|
||||
Due to the absence of additional convolutions during downsampling and upsampling, this method more seamlessly inherits the weights from the SD2.1 VAE, leading to improved initialization of our VAE.
|
||||
|
||||
<img src="https://s21.ax1x.com/2024/07/24/pkHrHx0.png" width=768>
|
||||
|
||||
|
||||
#### Training Details
|
||||
|
||||
|
||||
As with v1.1.0, we initialize from the [SD2.1 VAE](https://huggingface.co/stabilityai/sd-vae-ft-mse) using tail initialization. We perform the first phase of training on the Kinetic400 video dataset, then use the EMA weights from this phase to initialize the second phase, which is fine-tuned on high-quality data (collected in v1.1.0). All training is conducted on 25-frame 256×256 videos using **one A100 node**.
|
||||
|
||||
|
||||
| Training stage | Dataset | Training steps |
|
||||
|---|---|---|
|
||||
| 1 | K400 | 200,000 |
|
||||
| 2 | collected in v1.1.0 | 450,000 |
|
||||
|
||||
|
||||
#### Evaluation
|
||||
|
||||
We evaluated our VAE on the validation sets of two video datasets: [Webvid](https://github.com/m-bain/webvid) and [Panda70m](https://github.com/snap-research/Panda-70M/), and compared it with our [v1.1.0](https://github.com/PKU-YuanGroup/Open-Sora-Plan/blob/main/docs/Report-v1.1.0.md), [SD2.1 VAE](https://huggingface.co/stabilityai/sd-vae-ft-mse), [CV-VAE](https://github.com/AILab-CVC/CV-VAE), and [Open-Sora's VAE](https://github.com/hpcaitech/Open-Sora). The Webvid validation set contains 5k videos, while the Panda70m validation set has 6k videos. The videos were resized to 256 pixels on the short side, center-cropped to 256x256, and then 33 consecutive frames were extracted. We used PSNR, SSIM, and LPIPS metrics, and measured the encoding speed on an A100 GPU. The specific results are as follows:
|
||||
|
||||
|
||||
**WebVid**
|
||||
|
||||
| Model | Compress Ratio |PNSR↑ | SSIM↑ |LPIPS↓ |
|
||||
|---|---|---|---|---|
|
||||
| SD2-1 VAE | 1x8x8 | 30.19 | 0.8379 | 0.0568 |
|
||||
| SVD VAE | 1x8x8 |<ins>31.15</ins> |<ins>0.8686</ins> | **0.0547** |
|
||||
| CV-VAE | 4x8x8 | 30.76 | 0.8566 | 0.0803 |
|
||||
| Open-Sora VAE | 4x8x8 | 31.12 | 0.8569 | 0.1003 |
|
||||
| Open-Sora Plan v1.1 | 4x8x8 | 30.26 | 0.8597 |<ins>0.0551</ins> |
|
||||
| Open-Sora Plan v1.2 | 4x8x8| **31.16** | **0.8694** | 0.0586 |
|
||||
|
||||
**Panda70M**
|
||||
|
||||
| Model | Compress Ratio| PNSR↑ | SSIM↑ |LPIPS↓ |
|
||||
|---|---|---|---|---|
|
||||
| SD2-1 VAE | 1x8x8 |30.40 | 0.8894 | 0.0396 |
|
||||
| SVD VAE | 1x8x8 |<ins>31.00</ins> | **0.9058** | **0.0379** |
|
||||
| CV-VAE | 4x8x8| 29.57 | 0.8795 | 0.0673 |
|
||||
| Open-Sora VAE | 4x8x8 | **31.06** | 0.8969 | 0.0666 |
|
||||
| Open-Sora Plan v1.1 | 4x8x8 | 29.16 | 0.8844 | 0.0481 |
|
||||
| Open-Sora Plan v1.2 | 4x8x8| 30.49 |<ins>0.8970</ins> |<ins>0.0454</ins>|
|
||||
|
||||
**Encode Time on A100**
|
||||
|
||||
|Input Size| CV-VAE | Open-Sora | Open-Sora Plan v1.1 | Open-Sora Plan v1.2 |
|
||||
|---|---|---|---|---|
|
||||
| 33x256x256 | 0.186 | 0.147 |<ins>0.104</ins> | **0.102** |
|
||||
| 81x256x256 | 0.465 | 0.357 |<ins>0.243</ins> | **0.242** |
|
||||
|
||||
### Training Text-to-Video Diffusion Model
|
||||
|
||||
#### Model Structure
|
||||
|
||||
The most significant change is that we **replaced all 2+1D Transformer blocks with 3D full attention blocks**. Each video is first processed by a patch embedding layer, which downsamples the spatial dimensions by a factor of 2. The video is then flattened into a one-dimensional sequence across the frame, width, and height dimensions. We replaced [T5-XXL](https://huggingface.co/DeepFloyd/t5-v1_1-xxl) with [mT5-XXL](https://huggingface.co/google/mt5-xxl) to enhance multilingual adaptation. Additionally, we incorporated RoPE.
|
||||
|
||||
|
||||
### Sequence Parallelism
|
||||
|
||||
Due to the high computational complexity of 3D full attention, we must allocate a video across 2 GPUs for parallel processing when training with long-duration and high-resolution videos. We can control the number of GPUs used for a video sample by adjusting the batch size on a node. For example, with `sp_size=8` and `train_sp_batch_size=4`, 2 GPUs are used for a single sample. **We support sequence parallelism for both training and inference**.
|
||||
|
||||
**Training on 93×720p**, we report speed on H100.
|
||||
|
||||
| GPU (sp_size) | batch size | Enable sp | Train_sp_batch_size | Speed | Step per day |
|
||||
|---|---|---|---|---|---|
|
||||
|8|8|×|-|100s/step|~850|
|
||||
|8|-|√|4|53s/step|~1600|
|
||||
|8|-|√|2|27s/step|~3200|
|
||||
|
||||
**Inference on 93×720p**, we report speed on H100.
|
||||
|
||||
| Size | 1 GPU | 8 GPUs |
|
||||
|---|---|---|
|
||||
|29×720p|420s/100step|80s/100step|
|
||||
|93×720p|3400s/100step|450s/100step|
|
||||
|
||||
#### Dynamic training
|
||||
|
||||
Deep neural networks are typically trained using batched inputs. For efficient hardware processing, batch shapes are fixed, leading to a fixed data size. This requires either cropping or padding images to a uniform size, both of which have drawbacks: cropping degrades performance, while padding is inefficient and results in significant information loss. Generally, there are three methods for training with arbitrary token counts: Patch n' Pack, bucket, and pad-mask.
|
||||
|
||||
|
||||
|
||||
**Patch n' Pack** ([NaViT](https://arxiv.org/abs/2307.06304)): bypasses the fixed sequence length limitation by combining tokens from multiple samples into a new sample. This approach allows variable-resolution images while maintaining aspect ratios by packaging multiple samples together, thereby reducing training time and enhancing performance and flexibility. However, this method involves significant code modifications and requires re-adaptation when exploring different model architectures in fields with unstable model designs.
|
||||
|
||||
|
||||
**Bucket** ([Pixart-alpha](https://arxiv.org/abs/2310.00426), [Open-Sora](https://github.com/hpcaitech/Open-Sora)): This method packages data of different resolutions into buckets, sampling batches from each bucket to ensure same resolution within each batch. It requires minimal code modifications to the model, mainly adjusting the data sampling strategy.
|
||||
|
||||
**Pad-mask** ([FiT](https://arxiv.org/abs/2402.12376), our v1.0/v1.1): This method sets a maximum resolution and pads all data to this resolution, generating a corresponding mask. Although the approach is straightforward, it is computationally inefficient.
|
||||
|
||||
We believe that current video generation models are still in an exploratory phase. Extensive modifications to model code during this period can incur unnecessary development costs. The pad-mask method, while straightforward, is computationally inefficient and can waste resources in video, which involves dense computations. Ultimately, we chose the bucket strategy, which requires no modifications to the model code. Next, we will explain how our bucket strategy supports arbitrary lengths and resolutions. For simplicity, we will use video duration as an example:
|
||||
|
||||
<img src="https://s21.ax1x.com/2024/07/24/pkHr4aQ.png" width=768>
|
||||
|
||||
|
||||
We define a megabatch as the total data processed in a single step across all GPUs. A megabatch can be divided into multiple batches, with each batch corresponding to the data processed by a single GPU.
|
||||
|
||||
**Sort by frame**: The first step is to count the number of frames in all video data and sort them. This step aims to group similar data together, with sorting being one method to achieve this.
|
||||
|
||||
**Group megabatch**: Next, all data is divided into groups, each forming a megabatch. Since all data is pre-sorted, most videos within a megabatch have the same number of frames. However, there will always be boundary cases, such as having both 61-frame and 1-frame videos in a single megabatch.
|
||||
|
||||
**Re-organize megabatch**: We re-organize these special megabatches, which actually constitute a small proportion. We randomly replace the minority data in the megabatch with the majority data, thus re-organizing it into a megabatch with same frame counts.
|
||||
|
||||
**Shuffle megabatch**: To ensure data randomness, we shuffle both within each megabatch and between different megabatches.
|
||||
|
||||
When supporting dynamic resolutions, we simply replace each sample's frame sequence with (frame × height × width). This method ensures that the data dimension processed by each GPU in every step is the same, preventing situations where GPU1 waits for GPU0 to finish processing a longer video. Moreover, it is entirely decoupled from the model code, serving as a plug-and-play video sampling strategy.
|
||||
|
||||
|
||||
#### Training stage
|
||||
|
||||
Similar to previous work, we use a multi-stage training approach. With the 3D DiT architecture, all parameters can be transferred from images to videos without loss. To explore training costs, all parameters of the diffusion model are trained from scratch. Therefore, we first train an text-to-image model, using the training strategy from [Pixart-alpha](https://arxiv.org/abs/2310.00426).
|
||||
|
||||
The video model is initialized with weights from a 480p image model. We first train 480p videos with 29 frames. Next, we adapt the weights to 720p resolution, training on approximately 6 million higher-quality (HQ) samples from Panda70M, filtered for aesthetic quality and motion. Finally, we refine the model with a more higher-quality (HQ) subset of 1 million samples. After that, we use a filtered data (collected in v1.1.0) for fine-tuning 93-frame 720p videos. Below is our training card. We release the annotation file [here](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.2.0/tree/main/anno_json).
|
||||
|
||||
| Name | Stage 1 | Stage 2 | Stage 3 | Stage 4 |Stage 5 |
|
||||
|---|---|---|---|---|---|
|
||||
| Training Video Size | 1×320×240 | 1×640×480 | 29×640×480 | 29×1280×720 | 93×1280×720 |
|
||||
| Training Step| 146k | 200k | 30k | 21k | 3k |
|
||||
| Compute (#Num x #Hours) | 32 Ascend × 81 | 32 Ascend × 142 | 128 Ascend × 38 | 256 H100 × 64 | 256 H100 × 84 |
|
||||
| Checkpoint | - | [HF](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.2.0/tree/main/1x480p) | [HF](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.2.0/tree/main/29x480p) | [HF](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.2.0/tree/main/29x720p) | [HF](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.2.0/tree/main/93x720p) |
|
||||
| Log | - | - | [wandb](https://api.wandb.ai/links/1471742727-Huawei/trdu2kba) | [wandb](https://api.wandb.ai/links/linbin/vvxvcd7s) | [wandb](https://api.wandb.ai/links/linbin/easg3qkl)
|
||||
| Training Data | [10M SAM](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.2.0/blob/main/anno_json/sam_image_11185255_resolution.json) | 5M internal image data | [6M HQ Panda70M](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.2.0/blob/main/anno_json/Panda70M_HQ6M.json) | [6M HQ Panda70M](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.2.0/blob/main/anno_json/Panda70M_HQ6M.json) | [1M HQ Panda70M](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.2.0/blob/main/anno_json/Panda70M_HQ1M.json) and [100k HQ data](https://huggingface.co/datasets/LanguageBind/Open-Sora-Plan-v1.2.0/tree/main/anno_json) (collected in v1.1.0) |
|
||||
|
||||
Additionally, we fine-tuned 3.5k steps from the final 93×720p to get [93×480p](https://huggingface.co/LanguageBind/Open-Sora-Plan-v1.2.0/tree/main/93x480p) for community research use.
|
||||
|
||||
### Training Image-to-Video Diffusion Model
|
||||
|
||||
#### Model Structure
|
||||
|
||||
<img src="https://s21.ax1x.com/2024/08/12/pApZZJf.png">
|
||||
|
||||
To reuse the weights of the Text-to-Video model, our Image-to-Video model is inspired by the Stable Diffusion Inpainting Model and adopts a strategy based on frame-level inpainting. By incorporating three types of information—original noise, masked video, and mask—under different control frame conditions, our model can generate coherent videos while ensuring flexibility in its usage.
|
||||
|
||||
Compared to the denoiser structure of the Text-to-Video model, the Inpainting Model's denoiser has only changed the number of channels in the `conv in` layer. To ensure the model has a good prior knowledge, we introduce the masked video and mask information through zero initialization. We believe this is due to the 2+1D structure's lack of ability to establish long-range information dependencies, and relying solely on attention in the temporal dimension makes it difficult to capture information changes under frame control. In Text-to-Video tasks, this phenomenon is not as evident because all frames share the same text prompt embedding. However, in Image-to-Video tasks, simply concatenating images in the channel dimension does not ensure the model can accurately capture changes between frames. This is because the model cannot directly replicate image information from the channels to reduce the loss, and the 2+1D structure's interaction solely on the temporal axis fails to allow the model to discern which information from the control frames can be utilized, especially there are significant differences between frames. Therefore, without a shared image-semantic information, the control frame information might not be effectively conveyed to each frame.
|
||||
|
||||
##### About Semantic Adapter
|
||||
|
||||
In previous models based on the Unet 2+1D architecture, it is necessary to input the control frames into the CLIP model to obtain semantic embeddings. These semantic embeddings are then injected into the denoiser through cross-attention. The structure that extracts CLIP embeddings and injects them into the denoiser is commonly referred to as a semantic adapter.
|
||||
|
||||
In the 2+1D architecture, the semantic adapter is commonly present. Additionally, papers like [DynamiCrafter](https://arxiv.org/abs/2310.12190) have pointed out that incorporating the semantic adapter helps maintain stability in the generated videos. We believe this is because the 2+1D structure lacks the ability to establish long-range information dependencies, and relying solely on attention in the temporal dimension makes it difficult to capture information changes under frame control. In the Text-to-Video task, this phenomenon is not as evident because all frames share the same text prompt embedding. However, in the Image-to-Video task, without shared semantic information, it may lead to the inability to effectively transfer control frame information to each individual frame.
|
||||
|
||||
<center>
|
||||
<figure>
|
||||
<img src="https://github.com/user-attachments/assets/06df193a-fe89-42c1-8c01-fb3b7c2be0e3" height=400 />
|
||||
<img src="https://github.com/user-attachments/assets/09906df4-ab9f-443d-8d38-512e16075b0c" height=400 />
|
||||
</figure>
|
||||
</center>
|
||||
|
||||
We conducted a simple comparison of the performance of using the Inpainting Model under the 2+1D structure (Open-Sora Plan v1.1, left in the figure) versus the 3D structure (Open-Sora Plan v1.2, right in the figure). With the same number of optimization steps, the probability of unstable visual performance in the 2+1D structure was significantly higher than in the 3D structure. Even at convergence, the 2+1D structure's visual stability was still inferior to that of the 3D structure, and it was even worse than the early training stages of the 3D structure.
|
||||
|
||||
## Future Work and Discussion
|
||||
|
||||
#### CausalVideoVAE
|
||||
We observed that high-frequency motion information in videos tends to exhibit jitter, and increasing training duration and data volume does not significantly alleviate this issue. In videos, compressing the duration while maintaining the original latent dimension can lead to significant information loss. A more robust VAE will be released in the next version.
|
||||
|
||||
#### Diffusion Model
|
||||
We replaced T5 with mT5 to enhance multilingual capabilities, but this capability is limited as our training data is currently only in English. The multilingual ability primarily comes from the mT5 mapping space. We will explore additional text encoders and expand the data in the next steps.
|
||||
|
||||
Our model performs well in generating character consistency, likely due to panda70m being a character-centric dataset. However, it still shows poor performance in text consistency and object generalization. We suspect this may be due to the limited amount of data the model has seen, as evidenced by the non-convergence of the loss in the final stage. **We hope to collaborate with the open-source community to optimize the 3D DiT architecture.**
|
||||
@@ -0,0 +1,2 @@
|
||||
/path/to/image_0.png
|
||||
/path/to/image_1_0.png,/path/to/image_1_1.png
|
||||
@@ -0,0 +1,38 @@
|
||||
import torch
|
||||
from torch.utils.data import DataLoader, Subset
|
||||
import sys
|
||||
sys.path.append(".")
|
||||
from opensora.models.ae.videobase import CausalVAEModel, CausalVAEDataset
|
||||
|
||||
num_workers = 4
|
||||
batch_size = 12
|
||||
|
||||
torch.manual_seed(0)
|
||||
torch.set_grad_enabled(False)
|
||||
|
||||
device = torch.device('cuda' if torch.cuda.is_available() else 'cpu')
|
||||
|
||||
pretrained_model_name_or_path = 'results/causalvae/checkpoint-26000'
|
||||
data_path = '/remote-home1/dataset/UCF-101'
|
||||
video_num_frames = 17
|
||||
resolution = 128
|
||||
sample_rate = 10
|
||||
|
||||
vae = CausalVAEModel.load_from_checkpoint(pretrained_model_name_or_path)
|
||||
vae.to(device)
|
||||
|
||||
dataset = CausalVAEDataset(data_path, sequence_length=video_num_frames, resolution=resolution, sample_rate=sample_rate)
|
||||
subset_indices = list(range(1000))
|
||||
subset_dataset = Subset(dataset, subset_indices)
|
||||
loader = DataLoader(subset_dataset, batch_size=8, pin_memory=True)
|
||||
|
||||
all_latents = []
|
||||
for video_data in loader:
|
||||
video_data = video_data['video'].to(device)
|
||||
latents = vae.encode(video_data).sample()
|
||||
all_latents.append(video_data.cpu())
|
||||
|
||||
all_latents_tensor = torch.cat(all_latents)
|
||||
std = all_latents_tensor.std().item()
|
||||
normalizer = 1 / std
|
||||
print(f'{normalizer = }')
|
||||
@@ -0,0 +1,20 @@
|
||||
A young man at his 20s is sitting on a piece of cloud in the sky, reading a book.
|
||||
An extreme close-up of an gray-haired man with a beard in his 60s, he is deep in thought pondering the history of the universe as he sits at a cafe in Paris, his eyes focus on people offscreen as they walk as he sits mostly motionless, he is dressed in a wool coat suit coat with a button-down shirt, he wears a brown beret and glasses and has a very professorial appearance, and the end he offers a subtle closed-mouth smile as if he found the answer to the mystery of life, the lighting is very cinematic with the golden light and the Parisian streets and city in the background, depth of field, cinematic 35mm film.
|
||||
A close-up of a woman’s face, illuminated by the soft light of dawn, her expression serene and content as she wakes up in a cozy bedroom.
|
||||
An intense close-up of a detective’s face, lit by a single desk lamp, his eyes scanning a wall covered in photos and notes, deep in thought.
|
||||
Audience members in a theater are captured in a series of medium shots, with a young man and woman in formal attire centrally positioned and illuminated by a spotlight effect.
|
||||
A soaring drone footage captures the majestic beauty of a coastal cliff, its red and yellow stratified rock faces rich in color and against the vibrant turquoise of the sea. Seabirds can be seen taking flight around the cliff's precipices. As the drone slowly moves from different angles, the changing sunlight casts shifting shadows that highlight the rugged textures of the cliff and the surrounding calm sea. The water gently laps at the rock base and the greenery that clings to the top of the cliff, and the scene gives a sense of peaceful isolation at the fringes of the ocean. The video captures the essence of pristine natural beauty untouched by human structures.
|
||||
a realistic 3d rendering of a female character with curly blonde hair and blue eyes. she is wearing a black tank top and has a neutral expression while facing the camera directly. the background is a plain blue sky, and the scene is devoid of any other objects or text. the character is detailed, with realistic textures and lighting, suitable for a video game or high-quality animation. there is no movement or additional action in the video. the focus is entirely on the character's appearance and realistic rendering.
|
||||
A panda strumming a guitar under a bamboo grove, its paws gently plucking the strings as a group of mesmerized rabbits watch, the music blending with the rustle of bamboo leaves. HD.
|
||||
A close-up of a woman with a vintage hairstyle and bright red lipstick, gazing seductively into the camera, the background blurred to keep the focus solely on her.
|
||||
In the jungle, a hidden temple stands guarded by statues of lions, their eyes glowing with emerald light, protecting secrets untold for millennia. 8K.
|
||||
A close-up of an old man’s weathered face, with deep wrinkles and a thick white mustache, looking out to sea, the wind gently blowing through his hair.
|
||||
An intense close-up of a soldier’s face, covered in dirt and sweat, his eyes filled with determination as he surveys the battlefield.
|
||||
A river that flows uphill, defying gravity as it returns lost treasures from the sea to the mountain top, each item telling a story of a voyage gone by. HD.
|
||||
A close-up of a man’s face, lit only by the glow of his computer screen, his eyes wide and unblinking as he discovers something shocking online.
|
||||
On a deserted island, palm trees sway to summon a rainstorm, their leaves conducting the wind like maestros, orchestrating a symphony of thunder and lightning. High Resolution.
|
||||
An extreme close-up of a middle-aged man’s face, with a five o’clock shadow, staring pensively into the distance as rain softly taps against the window beside him, his thoughts deep and contemplative.
|
||||
A close-up of a man’s face, his expression one of deep concentration as he works on a complex task.
|
||||
Drone view of waves crashing against the rugged cliffs along Big Sur's garay point beach.The crashing blue waters create white-tipped waves,while the golden light of the setting sun illuminates the rocky shore. A small island with a lighthouse sits in the distance, and green
|
||||
shrubbery covers the cliffs edge. The steep drop from the road down to the beach is adramatic feat, with the cliff's edges jutting out over the sea. This is a view that captures the raw beauty of the coast and the rugged landscape of the Pacific Coast Highway.
|
||||
a close-up shot of a woman standing in a dimly lit room. she is wearing a traditional chinese outfit, which includes a red and gold dress with intricate designs and a matching headpiece. the woman has her hair styled in an updo, adorned with a gold accessory. her makeup is done in a way that accentuates her features, with red lipstick and dark eyeshadow. she is looking directly at the camera with a neutral expression. the room has a rustic feel, with wooden beams and a stone wall visible in the background. the lighting in the room is soft and warm, creating a contrast with the woman's vibrant attire. there are no texts or other objects in the video. the style of the video is a portrait, focusing on the woman and her attire.
|
||||
@@ -0,0 +1,67 @@
|
||||
import sys
|
||||
from PIL import Image
|
||||
import torch
|
||||
from torchvision.transforms import ToTensor, Compose, Resize, Normalize, Lambda
|
||||
from torch.nn import functional as F
|
||||
import argparse
|
||||
import numpy as np
|
||||
from opensora.models import CausalVAEModelWrapper
|
||||
|
||||
def preprocess(video_data: torch.Tensor, short_size: int = 128) -> torch.Tensor:
|
||||
transform = Compose(
|
||||
[
|
||||
ToTensor(),
|
||||
Lambda(lambda x: 2. * x - 1.),
|
||||
Resize(size=short_size),
|
||||
]
|
||||
)
|
||||
outputs = transform(video_data)
|
||||
outputs = outputs.unsqueeze(0).unsqueeze(2)
|
||||
return outputs
|
||||
|
||||
def main(args: argparse.Namespace):
|
||||
image_path = args.image_path
|
||||
short_size = args.short_size
|
||||
device = args.device
|
||||
kwarg = {}
|
||||
|
||||
# vae = getae_wrapper(args.ae)(args.model_path, subfolder="vae", cache_dir='cache_dir', **kwarg).to(device)
|
||||
vae = CausalVAEModelWrapper(args.ae_path, **kwarg).to(device)
|
||||
if args.enable_tiling:
|
||||
vae.vae.enable_tiling()
|
||||
vae.vae.tile_overlap_factor = args.tile_overlap_factor
|
||||
vae.eval()
|
||||
vae = vae.to(device)
|
||||
vae = vae.half()
|
||||
|
||||
with torch.no_grad():
|
||||
x_vae = preprocess(Image.open(image_path), short_size)
|
||||
x_vae = x_vae.to(device, dtype=torch.float16) # b c t h w
|
||||
latents = vae.encode(x_vae)
|
||||
latents = latents.to(torch.float16)
|
||||
image_recon = vae.decode(latents) # b t c h w
|
||||
x = image_recon[0, 0, :, :, :]
|
||||
x = x.squeeze()
|
||||
x = x.detach().cpu().numpy()
|
||||
x = np.clip(x, -1, 1)
|
||||
x = (x + 1) / 2
|
||||
x = (255*x).astype(np.uint8)
|
||||
x = x.transpose(1,2,0)
|
||||
image = Image.fromarray(x)
|
||||
image.save(args.rec_path)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument('--image_path', type=str, default='')
|
||||
parser.add_argument('--rec_path', type=str, default='')
|
||||
parser.add_argument('--ae', type=str, default='')
|
||||
parser.add_argument('--ae_path', type=str, default='')
|
||||
parser.add_argument('--model_path', type=str, default='results/pretrained')
|
||||
parser.add_argument('--short_size', type=int, default=336)
|
||||
parser.add_argument('--device', type=str, default='cuda')
|
||||
parser.add_argument('--tile_overlap_factor', type=float, default=0.25)
|
||||
parser.add_argument('--enable_tiling', action='store_true')
|
||||
|
||||
args = parser.parse_args()
|
||||
main(args)
|
||||
@@ -0,0 +1,131 @@
|
||||
import math
|
||||
import random
|
||||
import argparse
|
||||
from typing import Optional
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import numpy.typing as npt
|
||||
import torch
|
||||
from PIL import Image
|
||||
from decord import VideoReader, cpu
|
||||
from torch.nn import functional as F
|
||||
from pytorchvideo.transforms import ShortSideScale
|
||||
from torchvision.transforms import Lambda, Compose
|
||||
from opensora.models import CausalVAEModelWrapper
|
||||
from opensora.dataset.transform import ToTensorVideo, CenterCropResizeVideo
|
||||
|
||||
|
||||
def array_to_video(image_array: npt.NDArray, fps: float = 30.0, output_file: str = 'output_video.mp4') -> None:
|
||||
height, width, channels = image_array[0].shape
|
||||
fourcc = cv2.VideoWriter_fourcc(*'mp4v')
|
||||
video_writer = cv2.VideoWriter(output_file, fourcc, float(fps), (width, height))
|
||||
|
||||
for image in image_array:
|
||||
image_rgb = cv2.cvtColor(image, cv2.COLOR_RGB2BGR)
|
||||
video_writer.write(image_rgb)
|
||||
|
||||
video_writer.release()
|
||||
|
||||
|
||||
def custom_to_video(x: torch.Tensor, fps: float = 2.0, output_file: str = 'output_video.mp4') -> None:
|
||||
x = x.detach().cpu()
|
||||
x = torch.clamp(x, -1, 1)
|
||||
x = (x + 1) / 2
|
||||
x = x.permute(0, 2, 3, 1).numpy()
|
||||
x = (255 * x).astype(np.uint8)
|
||||
array_to_video(x, fps=fps, output_file=output_file)
|
||||
return
|
||||
|
||||
|
||||
def read_video(video_path: str, num_frames: int, sample_rate: int) -> torch.Tensor:
|
||||
decord_vr = VideoReader(video_path, ctx=cpu(0))
|
||||
total_frames = len(decord_vr)
|
||||
sample_frames_len = sample_rate * num_frames
|
||||
|
||||
if total_frames > sample_frames_len:
|
||||
s = random.randint(0, total_frames - sample_frames_len - 1)
|
||||
s = 0
|
||||
e = s + sample_frames_len
|
||||
num_frames = num_frames
|
||||
else:
|
||||
s = 0
|
||||
e = total_frames
|
||||
num_frames = int(total_frames / sample_frames_len * num_frames)
|
||||
print(f'sample_frames_len {sample_frames_len}, only can sample {num_frames * sample_rate}', video_path,
|
||||
total_frames)
|
||||
|
||||
frame_id_list = np.linspace(s, e - 1, num_frames, dtype=int)
|
||||
video_data = decord_vr.get_batch(frame_id_list).asnumpy()
|
||||
video_data = torch.from_numpy(video_data)
|
||||
video_data = video_data.permute(3, 0, 1, 2) # (T, H, W, C) -> (C, T, H, W)
|
||||
return video_data
|
||||
|
||||
|
||||
def preprocess(video_data: torch.Tensor, height: int = 128, width: int = 128) -> torch.Tensor:
|
||||
transform = Compose(
|
||||
[
|
||||
ToTensorVideo(),
|
||||
CenterCropResizeVideo((height, width)),
|
||||
Lambda(lambda x: 2. * x - 1.)
|
||||
]
|
||||
)
|
||||
|
||||
video_outputs = transform(video_data)
|
||||
video_outputs = torch.unsqueeze(video_outputs, 0)
|
||||
|
||||
return video_outputs
|
||||
|
||||
|
||||
def main(args: argparse.Namespace):
|
||||
device = args.device
|
||||
kwarg = {}
|
||||
# vae = getae_wrapper(args.ae)(args.model_path, subfolder="vae", cache_dir='cache_dir', **kwarg).to(device)
|
||||
vae = CausalVAEModelWrapper(args.ae_path, **kwarg).to(device)
|
||||
if args.enable_tiling:
|
||||
vae.vae.enable_tiling()
|
||||
vae.vae.tile_overlap_factor = args.tile_overlap_factor
|
||||
vae.vae.tile_overlap_factor = args.tile_overlap_factor
|
||||
if args.save_memory:
|
||||
vae.vae.tile_sample_min_size = 256
|
||||
vae.vae.tile_latent_min_size = 32
|
||||
vae.vae.tile_sample_min_size_t = 29
|
||||
vae.vae.tile_latent_min_size_t = 8
|
||||
vae.eval()
|
||||
vae = vae.to(device)
|
||||
vae = vae.half()
|
||||
|
||||
with torch.no_grad():
|
||||
x_vae = preprocess(read_video(args.video_path, args.num_frames, args.sample_rate), args.height,
|
||||
args.width)
|
||||
print(x_vae.shape)
|
||||
x_vae = x_vae.to(device, dtype=torch.float16) # b c t h w
|
||||
latents = vae.encode(x_vae)
|
||||
print(latents.shape)
|
||||
latents = latents.to(torch.float16)
|
||||
video_recon = vae.decode(latents) # b t c h w
|
||||
print(video_recon.shape)
|
||||
|
||||
custom_to_video(video_recon[0], fps=args.fps, output_file=args.rec_path)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument('--video_path', type=str, default='')
|
||||
parser.add_argument('--rec_path', type=str, default='')
|
||||
parser.add_argument('--ae', type=str, default='')
|
||||
parser.add_argument('--ae_path', type=str, default='')
|
||||
parser.add_argument('--model_path', type=str, default='results/pretrained')
|
||||
parser.add_argument('--fps', type=int, default=30)
|
||||
parser.add_argument('--height', type=int, default=336)
|
||||
parser.add_argument('--width', type=int, default=336)
|
||||
parser.add_argument('--num_frames', type=int, default=100)
|
||||
parser.add_argument('--sample_rate', type=int, default=1)
|
||||
parser.add_argument('--device', type=str, default="cuda")
|
||||
parser.add_argument('--tile_overlap_factor', type=float, default=0.25)
|
||||
parser.add_argument('--tile_sample_min_size', type=int, default=256)
|
||||
parser.add_argument('--enable_tiling', action='store_true')
|
||||
parser.add_argument('--save_memory', action='store_true')
|
||||
|
||||
args = parser.parse_args()
|
||||
main(args)
|
||||
@@ -0,0 +1 @@
|
||||
#
|
||||
@@ -0,0 +1,133 @@
|
||||
import torch
|
||||
import torch.distributed as dist
|
||||
from einops import rearrange
|
||||
from opensora.acceleration.parallel_states import hccl_info, lccl_info, enable_LCCL
|
||||
try:
|
||||
from lcalib.functional import lcal_all2allvc
|
||||
except:
|
||||
lcal_all2allvc = None
|
||||
|
||||
def broadcast(input_: torch.Tensor):
|
||||
sp_size = hccl_info.world_size
|
||||
src = hccl_info.rank // sp_size * sp_size
|
||||
dist.broadcast(input_, src=src, group=hccl_info.group)
|
||||
|
||||
_COUNT = 0
|
||||
def _all_to_all(
|
||||
input_: torch.Tensor,
|
||||
scatter_dim: int,
|
||||
gather_dim: int,
|
||||
):
|
||||
group = hccl_info.group
|
||||
sp_size = hccl_info.world_size
|
||||
input_list = [t.contiguous() for t in torch.tensor_split(input_, sp_size, scatter_dim)]
|
||||
output_list = [torch.empty_like(input_list[0]) for _ in range(sp_size)]
|
||||
dist.all_to_all(output_list, input_list, group=group)
|
||||
return torch.cat(output_list, dim=gather_dim).contiguous()
|
||||
|
||||
def _single_all_to_all(
|
||||
input_: torch.Tensor,
|
||||
scatter_dim: int,
|
||||
gather_dim: int,
|
||||
enable_HCCL=False,
|
||||
):
|
||||
if enable_LCCL:
|
||||
sp_size = lccl_info.world_size
|
||||
else:
|
||||
sp_size = hccl_info.world_size
|
||||
inp_shape = list(input_.shape)
|
||||
inp_shape[scatter_dim] = inp_shape[scatter_dim] // sp_size
|
||||
if scatter_dim < 1:
|
||||
input_t = input_.reshape(
|
||||
[sp_size, inp_shape[scatter_dim]] + \
|
||||
inp_shape[scatter_dim + 1:]
|
||||
)
|
||||
else:
|
||||
# transpose groups of heads with the seq-len parallel dimension, so that we can scatter them!
|
||||
input_t = input_.reshape(
|
||||
[-1, sp_size, inp_shape[scatter_dim]] + \
|
||||
inp_shape[scatter_dim + 1:]
|
||||
).transpose(0, 1).contiguous()
|
||||
|
||||
output = torch.empty_like(input_t)
|
||||
if enable_LCCL and not enable_HCCL:
|
||||
matrix_count = torch.ones([sp_size, sp_size], dtype=torch.int64, device=input_t.device) * (
|
||||
input_t.numel() // sp_size)
|
||||
lcal_all2allvc(input_t, output, matrix_count, lccl_info.group)
|
||||
else:
|
||||
dist.all_to_all_single(output, input_t, group=hccl_info.group)
|
||||
# if scattering the seq-dim, transpose the heads back to the original dimension
|
||||
if scatter_dim < 1:
|
||||
output = output.transpose(0, 1).contiguous()
|
||||
|
||||
return output.reshape(
|
||||
inp_shape[: gather_dim] + [inp_shape[gather_dim] * sp_size, ] + inp_shape[gather_dim + 1:])
|
||||
|
||||
|
||||
class _AllToAll(torch.autograd.Function):
|
||||
"""All-to-all communication.
|
||||
|
||||
Args:
|
||||
input_: input matrix
|
||||
process_group: communication group
|
||||
scatter_dim: scatter dimension
|
||||
gather_dim: gather dimension
|
||||
"""
|
||||
|
||||
@staticmethod
|
||||
def forward(ctx, input_, scatter_dim, gather_dim, all_to_all_func):
|
||||
ctx.scatter_dim = scatter_dim
|
||||
ctx.gather_dim = gather_dim
|
||||
ctx.all_to_all = all_to_all_func
|
||||
output = ctx.all_to_all(input_, scatter_dim, gather_dim)
|
||||
return output
|
||||
|
||||
@staticmethod
|
||||
def backward(ctx, grad_output):
|
||||
grad_output = ctx.all_to_all(
|
||||
grad_output,
|
||||
ctx.gather_dim,
|
||||
ctx.scatter_dim,
|
||||
)
|
||||
return (
|
||||
grad_output,
|
||||
None,
|
||||
None,
|
||||
None,
|
||||
)
|
||||
|
||||
def all_to_all_SBH(
|
||||
input_: torch.Tensor,
|
||||
scatter_dim: int = 1,
|
||||
gather_dim: int = 0,
|
||||
):
|
||||
return _AllToAll.apply(input_, scatter_dim, gather_dim, _single_all_to_all)
|
||||
|
||||
def all_to_all_BSND(
|
||||
input_: torch.Tensor,
|
||||
scatter_dim: int = 2,
|
||||
gather_dim: int = 1,
|
||||
):
|
||||
return _AllToAll.apply(input_, scatter_dim, gather_dim, _all_to_all)
|
||||
|
||||
|
||||
def prepare_parallel_data(hidden_states, encoder_hidden_states, attention_mask, encoder_attention_mask, use_image_num):
|
||||
def all_to_all(hidden_states, encoder_hidden_states, attention_mask, encoder_attention_mask):
|
||||
hidden_states = _single_all_to_all(hidden_states, scatter_dim=2, gather_dim=0, enable_HCCL=True)
|
||||
encoder_hidden_states = _single_all_to_all(encoder_hidden_states, scatter_dim=1, gather_dim=0, enable_HCCL=True)
|
||||
attention_mask = _single_all_to_all(attention_mask, scatter_dim=1, gather_dim=0, enable_HCCL=True)
|
||||
encoder_attention_mask = _single_all_to_all(encoder_attention_mask, scatter_dim=1, gather_dim=0, enable_HCCL=True)
|
||||
return hidden_states, encoder_hidden_states, attention_mask, encoder_attention_mask
|
||||
|
||||
sp_size = hccl_info.world_size
|
||||
frame = hidden_states.shape[2]
|
||||
assert frame % sp_size == 0, "frame should be a multiple of sp_size"
|
||||
|
||||
encoder_hidden_states = rearrange(encoder_hidden_states, 'b 1 (n x) h -> b n x h',
|
||||
n=sp_size, x=encoder_hidden_states.shape[2]//sp_size).contiguous()
|
||||
hidden_states, encoder_hidden_states, attention_mask, encoder_attention_mask = all_to_all(hidden_states,
|
||||
encoder_hidden_states,
|
||||
attention_mask.repeat(1, sp_size, 1, 1),
|
||||
encoder_attention_mask.repeat(1, sp_size, 1))
|
||||
|
||||
return hidden_states, encoder_hidden_states, attention_mask, encoder_attention_mask, use_image_num
|
||||
@@ -0,0 +1,57 @@
|
||||
import torch
|
||||
import torch_npu
|
||||
import torch.distributed as dist
|
||||
import os
|
||||
try:
|
||||
from lcalib.functional import lcal_initialize
|
||||
enable_LCCL = True
|
||||
except:
|
||||
lcal_initialize = None
|
||||
enable_LCCL = False
|
||||
class COMM_INFO:
|
||||
def __init__(self):
|
||||
self.group = None
|
||||
self.world_size = 0
|
||||
self.rank = -1
|
||||
|
||||
lccl_info = COMM_INFO()
|
||||
hccl_info = COMM_INFO()
|
||||
_SEQUENCE_PARALLEL_STATE = False
|
||||
def initialize_sequence_parallel_state(sequence_parallel_size):
|
||||
global _SEQUENCE_PARALLEL_STATE
|
||||
if sequence_parallel_size > 1:
|
||||
_SEQUENCE_PARALLEL_STATE = True
|
||||
initialize_sequence_parallel_group(sequence_parallel_size)
|
||||
|
||||
def set_sequence_parallel_state(state):
|
||||
global _SEQUENCE_PARALLEL_STATE
|
||||
_SEQUENCE_PARALLEL_STATE = state
|
||||
|
||||
def get_sequence_parallel_state():
|
||||
return _SEQUENCE_PARALLEL_STATE
|
||||
|
||||
def initialize_sequence_parallel_group(sequence_parallel_size):
|
||||
"""Initialize the sequence parallel group."""
|
||||
rank = int(os.getenv('RANK', '0'))
|
||||
world_size = int(os.getenv("WORLD_SIZE", '1'))
|
||||
assert world_size % sequence_parallel_size == 0, "world_size must be divisible by sequence_parallel_size"
|
||||
# hccl
|
||||
hccl_info.world_size = sequence_parallel_size
|
||||
hccl_info.rank = rank
|
||||
num_sequence_parallel_groups: int = world_size // sequence_parallel_size
|
||||
for i in range(num_sequence_parallel_groups):
|
||||
ranks = range(i * sequence_parallel_size, (i + 1) * sequence_parallel_size)
|
||||
group = dist.new_group(ranks)
|
||||
if rank in ranks:
|
||||
hccl_info.group = group
|
||||
|
||||
if enable_LCCL:
|
||||
assert sequence_parallel_size == 8, "sequence_parallel_size should be 8 when enable_LCCL is True"
|
||||
rank %= sequence_parallel_size
|
||||
lccl_info.world_size = sequence_parallel_size
|
||||
lccl_info.group = lcal_initialize(rank, sequence_parallel_size)
|
||||
lccl_info.rank = rank
|
||||
|
||||
def destroy_sequence_parallel_group():
|
||||
"""Destroy the sequence parallel group."""
|
||||
dist.destroy_process_group()
|
||||
@@ -0,0 +1,458 @@
|
||||
# Copyright (c) Microsoft Corporation.
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
|
||||
# DeepSpeed Team
|
||||
|
||||
from collections import OrderedDict
|
||||
import torch
|
||||
import sys
|
||||
import os
|
||||
from torch._utils import _flatten_dense_tensors, _unflatten_dense_tensors
|
||||
from deepspeed import comm as dist
|
||||
from deepspeed.runtime.constants import PIPE_REPLICATED
|
||||
from deepspeed.runtime import ZeROOptimizer
|
||||
from packaging import version as pkg_version
|
||||
|
||||
from deepspeed.git_version_info import version
|
||||
from deepspeed.runtime.utils import (get_global_norm_of_tensors, clip_tensors_by_global_norm, DummyOptim,
|
||||
align_dense_tensors, all_gather_dp_groups, bwc_tensor_model_parallel_rank,
|
||||
is_model_parallel_parameter, see_memory_usage, graph_process)
|
||||
|
||||
from deepspeed.utils import link_hp_params, fragment_address
|
||||
from deepspeed.checkpoint import enable_universal_checkpoint
|
||||
from deepspeed.checkpoint.constants import (DS_VERSION, PARTITION_COUNT, BASE_OPTIMIZER_STATE,
|
||||
SINGLE_PARTITION_OF_FP32_GROUPS, CLIP_GRAD, GROUP_PADDINGS,
|
||||
PARAM_SLICE_MAPPINGS)
|
||||
|
||||
setattr(sys.modules[__name__], 'fragment_address', fragment_address)
|
||||
|
||||
|
||||
def contigous_flatten(tensors):
|
||||
return _flatten_dense_tensors([tensor.contiguous() for tensor in tensors])
|
||||
|
||||
|
||||
class BF16_Optimizer(ZeROOptimizer):
|
||||
|
||||
def __init__(self,
|
||||
init_optimizer,
|
||||
param_names,
|
||||
mpu=None,
|
||||
clip_grad=0.0,
|
||||
norm_type=2,
|
||||
allgather_bucket_size=5000000000,
|
||||
dp_process_group=None,
|
||||
timers=None,
|
||||
grad_acc_dtype=None,
|
||||
graph_harvesting=False):
|
||||
# super().__init__()
|
||||
# base_class = ZeROOptimizer.__bases__[0]
|
||||
# # 直接调用基类的 __init__ 方法
|
||||
# base_class.__init__()
|
||||
see_memory_usage('begin bf16_optimizer', force=True)
|
||||
self.timers = timers
|
||||
self.optimizer = init_optimizer
|
||||
self.param_names = param_names
|
||||
self.using_real_optimizer = not isinstance(self.optimizer, DummyOptim)
|
||||
|
||||
assert grad_acc_dtype in [torch.float32, torch.bfloat16
|
||||
], f"BF16Optimizer: Unsupported gradient accumulation data type: {grad_acc_dtype}"
|
||||
self.grad_acc_dtype = grad_acc_dtype
|
||||
|
||||
self.clip_grad = clip_grad
|
||||
self.norm_type = norm_type
|
||||
self.mpu = mpu
|
||||
self.allgather_bucket_size = int(allgather_bucket_size)
|
||||
self.dp_process_group = dp_process_group
|
||||
self.dp_rank = dist.get_rank(group=self.dp_process_group)
|
||||
self.real_dp_process_group = [dp_process_group for i in range(len(self.optimizer.param_groups))]
|
||||
|
||||
# Use torch (un)flatten ops
|
||||
self.flatten = contigous_flatten
|
||||
self.unflatten = _unflatten_dense_tensors
|
||||
|
||||
#align nccl all-gather send buffers to 4-bye boundary
|
||||
self.nccl_start_alignment_factor = 16
|
||||
|
||||
# Build BF16/FP32 groups
|
||||
self.bf16_groups = []
|
||||
self.bf16_groups_flat = []
|
||||
self.bf16_partitioned_groups = []
|
||||
|
||||
self.fp32_groups_flat_partition = []
|
||||
|
||||
# Maintain different fp32 gradients views for convenience
|
||||
self.fp32_groups_gradients = []
|
||||
self.fp32_groups_gradient_dict = {}
|
||||
self.fp32_groups_gradients_flat = []
|
||||
self.fp32_groups_actual_gradients_flat = []
|
||||
self.fp32_groups_gradient_flat_partition = []
|
||||
self.fp32_groups_has_gradients = []
|
||||
|
||||
self.group_paddings = []
|
||||
self.graph_harvesting = graph_harvesting
|
||||
if self.using_real_optimizer:
|
||||
self._setup_for_real_optimizer()
|
||||
|
||||
see_memory_usage('end bf16_optimizer', force=True)
|
||||
|
||||
def _setup_for_real_optimizer(self):
|
||||
dp_world_size = dist.get_world_size(group=self.dp_process_group)
|
||||
self.partition_count = [dp_world_size for i in range(len(self.optimizer.param_groups))]
|
||||
|
||||
for i, param_group in enumerate(self.optimizer.param_groups):
|
||||
see_memory_usage(f'before initializing group {i}', force=True)
|
||||
|
||||
partition_id = dist.get_rank(group=self.real_dp_process_group[i])
|
||||
|
||||
# grab the original list
|
||||
trainable_parameters = [param for param in param_group['params'] if param.requires_grad]
|
||||
self.bf16_groups.append(trainable_parameters)
|
||||
|
||||
# create flat bf16 params
|
||||
self.bf16_groups_flat.append(
|
||||
self._flatten_dense_tensors_aligned(self.bf16_groups[i],
|
||||
self.nccl_start_alignment_factor * dp_world_size))
|
||||
|
||||
# Make bf16 params point to flat tensor storage
|
||||
self._update_storage_to_flattened_tensor(tensor_list=self.bf16_groups[i],
|
||||
flat_tensor=self.bf16_groups_flat[i])
|
||||
|
||||
# divide flat weights into equal sized partitions
|
||||
partition_size = self.bf16_groups_flat[i].numel() // dp_world_size
|
||||
bf16_dp_partitions = [
|
||||
self.bf16_groups_flat[i].narrow(0, dp_index * partition_size, partition_size)
|
||||
for dp_index in range(dp_world_size)
|
||||
]
|
||||
self.bf16_partitioned_groups.append(bf16_dp_partitions)
|
||||
|
||||
# create fp32 params partition
|
||||
self.fp32_groups_flat_partition.append(bf16_dp_partitions[partition_id].clone().float().detach())
|
||||
self.fp32_groups_flat_partition[i].requires_grad = True
|
||||
|
||||
num_elem_list = [t.numel() for t in self.bf16_groups[i]]
|
||||
|
||||
# create fp32 gradients
|
||||
self.fp32_groups_gradients_flat.append(
|
||||
torch.zeros_like(self.bf16_groups_flat[i], dtype=self.grad_acc_dtype))
|
||||
|
||||
# track individual fp32 gradients for entire model
|
||||
fp32_gradients = self._split_flat_tensor(flat_tensor=self.fp32_groups_gradients_flat[i],
|
||||
num_elem_list=num_elem_list)
|
||||
self.fp32_groups_gradients.append(fp32_gradients)
|
||||
self.fp32_groups_gradient_dict[i] = fp32_gradients
|
||||
|
||||
# flat tensor corresponding to actual fp32 gradients (i.e., minus alignment padding)
|
||||
length_without_padding = sum(num_elem_list)
|
||||
self.fp32_groups_actual_gradients_flat.append(
|
||||
torch.narrow(self.fp32_groups_gradients_flat[i], 0, 0, length_without_padding))
|
||||
|
||||
# flat tensor corresponding to gradient partition
|
||||
self.fp32_groups_gradient_flat_partition.append(
|
||||
torch.narrow(self.fp32_groups_gradients_flat[i], 0, partition_id * partition_size, partition_size))
|
||||
|
||||
# track fp32 gradient updates
|
||||
self.fp32_groups_has_gradients.append([False] * len(self.bf16_groups[i]))
|
||||
|
||||
# Record padding required for alignment
|
||||
if partition_id == dist.get_world_size(group=self.real_dp_process_group[i]) - 1:
|
||||
padding = self.bf16_groups_flat[i].numel() - length_without_padding
|
||||
else:
|
||||
padding = 0
|
||||
|
||||
self.group_paddings.append(padding)
|
||||
|
||||
# update optimizer param groups to reference fp32 params partition
|
||||
param_group['params'] = [self.fp32_groups_flat_partition[i]]
|
||||
|
||||
see_memory_usage(f'after initializing group {i}', force=True)
|
||||
|
||||
see_memory_usage('before initialize_optimizer', force=True)
|
||||
self.initialize_optimizer_states()
|
||||
see_memory_usage('end initialize_optimizer', force=True)
|
||||
|
||||
# Need optimizer states initialized before linking lp to optimizer state
|
||||
self._link_all_hp_params()
|
||||
self._enable_universal_checkpoint()
|
||||
self._param_slice_mappings = self._create_param_mapping()
|
||||
|
||||
def _enable_universal_checkpoint(self):
|
||||
for lp_param_group in self.bf16_groups:
|
||||
enable_universal_checkpoint(param_list=lp_param_group)
|
||||
|
||||
def _create_param_mapping(self):
|
||||
param_mapping = []
|
||||
for i, _ in enumerate(self.optimizer.param_groups):
|
||||
param_mapping_per_group = OrderedDict()
|
||||
for lp in self.bf16_groups[i]:
|
||||
if lp._hp_mapping is not None:
|
||||
lp_name = self.param_names[lp]
|
||||
param_mapping_per_group[lp_name] = lp._hp_mapping.get_hp_fragment_address()
|
||||
param_mapping.append(param_mapping_per_group)
|
||||
|
||||
return param_mapping
|
||||
|
||||
def _link_all_hp_params(self):
|
||||
dp_world_size = dist.get_world_size(group=self.dp_process_group)
|
||||
for i, _ in enumerate(self.optimizer.param_groups):
|
||||
# Link bf16 and fp32 params in partition
|
||||
partition_id = dist.get_rank(group=self.real_dp_process_group[i])
|
||||
partition_size = self.bf16_groups_flat[i].numel() // dp_world_size
|
||||
flat_hp_partition = self.fp32_groups_flat_partition[i]
|
||||
link_hp_params(lp_param_list=self.bf16_groups[i],
|
||||
flat_hp_partition=flat_hp_partition,
|
||||
gradient_dict=self.fp32_groups_gradient_dict,
|
||||
offload_gradient_dict=None,
|
||||
use_offload=False,
|
||||
param_group_index=i,
|
||||
partition_start=partition_id * partition_size,
|
||||
partition_size=partition_size,
|
||||
partition_optimizer_state=self.optimizer.state[flat_hp_partition],
|
||||
dp_group=self.real_dp_process_group[i])
|
||||
|
||||
def initialize_optimizer_states(self):
|
||||
"""Take an optimizer step with zero-valued gradients to allocate internal
|
||||
optimizer state.
|
||||
|
||||
This helps prevent memory fragmentation by allocating optimizer state at the
|
||||
beginning of training instead of after activations have been allocated.
|
||||
"""
|
||||
for param_partition, grad_partition in zip(self.fp32_groups_flat_partition,
|
||||
self.fp32_groups_gradient_flat_partition):
|
||||
# In case of grad acc dtype different than FP32, need to cast to high precision.
|
||||
param_partition.grad = grad_partition.to(
|
||||
param_partition.dtype) if grad_partition.dtype != param_partition.dtype else grad_partition
|
||||
|
||||
self.optimizer.step()
|
||||
|
||||
if self.grad_acc_dtype is not torch.float32:
|
||||
for param_partition in self.fp32_groups_flat_partition:
|
||||
param_partition.grad = None
|
||||
|
||||
self.clear_hp_grads()
|
||||
|
||||
def _split_flat_tensor(self, flat_tensor, num_elem_list):
|
||||
assert sum(num_elem_list) <= flat_tensor.numel()
|
||||
tensor_list = []
|
||||
offset = 0
|
||||
for num_elem in num_elem_list:
|
||||
dense_tensor = torch.narrow(flat_tensor, 0, offset, num_elem)
|
||||
tensor_list.append(dense_tensor)
|
||||
offset += num_elem
|
||||
|
||||
return tensor_list
|
||||
|
||||
def _update_storage_to_flattened_tensor(self, tensor_list, flat_tensor):
|
||||
updated_params = self.unflatten(flat_tensor, tensor_list)
|
||||
for p, q in zip(tensor_list, updated_params):
|
||||
p.data = q.data
|
||||
|
||||
def _flatten_dense_tensors_aligned(self, tensor_list, alignment):
|
||||
return self.flatten(align_dense_tensors(tensor_list, alignment))
|
||||
|
||||
@torch.no_grad()
|
||||
def step(self, closure=None):
|
||||
if closure is not None:
|
||||
raise NotImplementedError(f'{self.__class__} does not support closure.')
|
||||
|
||||
all_groups_norm = get_global_norm_of_tensors(input_tensors=self.get_grads_for_norm(),
|
||||
mpu=self.mpu,
|
||||
norm_type=self.norm_type,
|
||||
use_graph=self.graph_harvesting)
|
||||
self._global_grad_norm = all_groups_norm
|
||||
|
||||
assert all_groups_norm > 0.
|
||||
if self.clip_grad > 0.:
|
||||
clip_tensors_by_global_norm(input_tensors=self.get_grads_for_norm(for_clipping=True),
|
||||
max_norm=self.clip_grad,
|
||||
global_norm=all_groups_norm,
|
||||
mpu=self.mpu,
|
||||
use_graph=self.graph_harvesting)
|
||||
|
||||
self.optimizer.step()
|
||||
|
||||
self.update_lp_params()
|
||||
|
||||
self.clear_hp_grads()
|
||||
|
||||
def backward(self, loss, update_hp_grads=True, clear_lp_grads=False, **bwd_kwargs):
|
||||
"""Perform a backward pass and copy the low-precision gradients to the
|
||||
high-precision copy.
|
||||
|
||||
We copy/accumulate to the high-precision grads now to prevent accumulating in the
|
||||
bf16 grads after successive backward() calls (i.e., grad accumulation steps > 1)
|
||||
|
||||
The low-precision grads are deallocated during this procedure.
|
||||
"""
|
||||
self.clear_lp_grads()
|
||||
loss.backward(**bwd_kwargs)
|
||||
|
||||
if update_hp_grads:
|
||||
self.update_hp_grads(clear_lp_grads=clear_lp_grads)
|
||||
|
||||
@torch.no_grad()
|
||||
def update_hp_grads(self, clear_lp_grads=False):
|
||||
|
||||
def _update_hp_grads_func(clear_lp_grads=False):
|
||||
for i, group in enumerate(self.bf16_groups):
|
||||
for j, lp in enumerate(group):
|
||||
if lp.grad is None:
|
||||
continue
|
||||
hp_grad = self.fp32_groups_gradients[i][j]
|
||||
assert hp_grad is not None, \
|
||||
f'high precision param has no gradient, lp param_id = {id(lp)} group_info = [{i}][{j}]'
|
||||
hp_grad.data.add_(lp.grad.data.to(hp_grad.dtype).view(hp_grad.shape))
|
||||
lp._hp_grad = hp_grad
|
||||
self.fp32_groups_has_gradients[i][j] = True
|
||||
# clear gradients
|
||||
if clear_lp_grads:
|
||||
lp.grad._zero()
|
||||
|
||||
if self.graph_harvesting:
|
||||
graph_process(False, _update_hp_grads_func, clear_lp_grads)
|
||||
else:
|
||||
_update_hp_grads_func(clear_lp_grads)
|
||||
#cpu op
|
||||
for i, group in enumerate(self.bf16_groups):
|
||||
for j, lp in enumerate(group):
|
||||
if lp.grad is None:
|
||||
continue
|
||||
self.fp32_groups_has_gradients[i][j] = True
|
||||
|
||||
@torch.no_grad()
|
||||
def get_grads_for_reduction(self):
|
||||
return self.fp32_groups_gradients_flat
|
||||
|
||||
@torch.no_grad()
|
||||
def get_grads_for_norm(self, for_clipping=False):
|
||||
grads = []
|
||||
tensor_mp_rank = bwc_tensor_model_parallel_rank(mpu=self.mpu)
|
||||
for i, group in enumerate(self.bf16_groups):
|
||||
for j, lp in enumerate(group):
|
||||
if not for_clipping:
|
||||
if hasattr(lp, PIPE_REPLICATED) and lp.ds_pipe_replicated:
|
||||
continue
|
||||
|
||||
if not (tensor_mp_rank == 0 or is_model_parallel_parameter(lp)):
|
||||
continue
|
||||
|
||||
if not self.fp32_groups_has_gradients[i][j]:
|
||||
continue
|
||||
|
||||
grads.append(self.fp32_groups_gradients[i][j])
|
||||
|
||||
return grads
|
||||
|
||||
@torch.no_grad()
|
||||
def update_lp_params(self):
|
||||
for i, (bf16_partitions,
|
||||
fp32_partition) in enumerate(zip(self.bf16_partitioned_groups, self.fp32_groups_flat_partition)):
|
||||
partition_id = dist.get_rank(group=self.real_dp_process_group[i])
|
||||
bf16_partitions[partition_id].data.copy_(fp32_partition.data)
|
||||
# print_rank_0(f'update_lp_params {i=} {partition_id=}', force=True)
|
||||
# if i == 0:
|
||||
# print_rank_0(f'{fp32_partition[:10]=}', force=True)
|
||||
|
||||
all_gather_dp_groups(groups_flat=self.bf16_groups_flat,
|
||||
partitioned_param_groups=self.bf16_partitioned_groups,
|
||||
dp_process_group=self.real_dp_process_group,
|
||||
start_alignment_factor=self.nccl_start_alignment_factor,
|
||||
allgather_bucket_size=self.allgather_bucket_size)
|
||||
|
||||
def clear_hp_grads(self):
|
||||
for flat_gradients in self.fp32_groups_gradients_flat:
|
||||
flat_gradients.zero_()
|
||||
|
||||
for i, group in enumerate(self.fp32_groups_gradients):
|
||||
self.fp32_groups_has_gradients[i] = [False] * len(group)
|
||||
|
||||
def clear_lp_grads(self):
|
||||
for group in self.bf16_groups:
|
||||
for param in group:
|
||||
if param.grad is not None:
|
||||
# Using zero_() fixed memory address for graph replay
|
||||
param.grad.zero_()
|
||||
|
||||
def state_dict(self):
|
||||
state_dict = {}
|
||||
state_dict[CLIP_GRAD] = self.clip_grad
|
||||
state_dict[BASE_OPTIMIZER_STATE] = self.optimizer.state_dict()
|
||||
state_dict[SINGLE_PARTITION_OF_FP32_GROUPS] = self.fp32_groups_flat_partition
|
||||
state_dict[GROUP_PADDINGS] = self.group_paddings
|
||||
state_dict[PARTITION_COUNT] = self.partition_count
|
||||
state_dict[DS_VERSION] = version
|
||||
state_dict[PARAM_SLICE_MAPPINGS] = self._param_slice_mappings
|
||||
|
||||
return state_dict
|
||||
|
||||
# Restore base optimizer fp32 weights bfloat16 weights
|
||||
def _restore_from_bit16_weights(self):
|
||||
for i, group in enumerate(self.bf16_groups):
|
||||
partition_id = dist.get_rank(group=self.real_dp_process_group[i])
|
||||
for bf16_partitions, fp32_partition in zip(self.bf16_partitioned_groups, self.fp32_groups_flat_partition):
|
||||
fp32_partition.data.copy_(bf16_partitions[partition_id].data)
|
||||
|
||||
def refresh_fp32_params(self):
|
||||
self._restore_from_bit16_weights()
|
||||
|
||||
def load_state_dict(self,
|
||||
state_dict_list,
|
||||
checkpoint_folder,
|
||||
load_optimizer_states=True,
|
||||
load_from_fp32_weights=False,
|
||||
load_serial=None):
|
||||
if checkpoint_folder:
|
||||
self._load_universal_checkpoint(checkpoint_folder, load_optimizer_states, load_from_fp32_weights)
|
||||
else:
|
||||
self._load_legacy_checkpoint(state_dict_list, load_optimizer_states, load_from_fp32_weights)
|
||||
|
||||
def _load_legacy_checkpoint(self, state_dict_list, load_optimizer_states=True, load_from_fp32_weights=False):
|
||||
|
||||
dp_rank = dist.get_rank(group=self.dp_process_group)
|
||||
current_rank_sd = state_dict_list[dp_rank]
|
||||
|
||||
ckpt_version = current_rank_sd.get(DS_VERSION, False)
|
||||
assert ckpt_version, f"Empty ds_version in checkpoint, not clear how to proceed"
|
||||
ckpt_version = pkg_version.parse(ckpt_version)
|
||||
|
||||
self.clip_grad = current_rank_sd.get(CLIP_GRAD, self.clip_grad)
|
||||
|
||||
if load_optimizer_states:
|
||||
self.optimizer.load_state_dict(current_rank_sd[BASE_OPTIMIZER_STATE])
|
||||
|
||||
if load_from_fp32_weights:
|
||||
for current, saved in zip(self.fp32_groups_flat_partition,
|
||||
current_rank_sd[SINGLE_PARTITION_OF_FP32_GROUPS]):
|
||||
src_tensor = _get_padded_tensor(saved, current.numel())
|
||||
current.data.copy_(src_tensor.data)
|
||||
|
||||
if load_optimizer_states:
|
||||
self._link_all_hp_params()
|
||||
|
||||
def _load_universal_checkpoint(self, checkpoint_folder, load_optimizer_states, load_from_fp32_weights):
|
||||
self._load_hp_checkpoint_state(checkpoint_folder)
|
||||
|
||||
@property
|
||||
def param_groups(self):
|
||||
"""Forward the wrapped optimizer's parameters."""
|
||||
return self.optimizer.param_groups
|
||||
|
||||
def _load_hp_checkpoint_state(self, checkpoint_dir):
|
||||
checkpoint_dir = os.path.join(checkpoint_dir, "zero")
|
||||
tp_rank = bwc_tensor_model_parallel_rank(mpu=self.mpu)
|
||||
tp_world_size = self.mpu.get_slice_parallel_world_size()
|
||||
|
||||
for i, _ in enumerate(self.optimizer.param_groups):
|
||||
for lp in self.bf16_groups[i]:
|
||||
if lp._hp_mapping is not None:
|
||||
#print(f"Loading {self.param_names[lp]} {tp_rank=} {tp_world_size=}")
|
||||
lp.load_hp_checkpoint_state(os.path.join(checkpoint_dir, self.param_names[lp]), tp_rank,
|
||||
tp_world_size)
|
||||
|
||||
|
||||
def _get_padded_tensor(src_tensor, size):
|
||||
if src_tensor.numel() >= size:
|
||||
return src_tensor
|
||||
padded_tensor = torch.zeros(size, dtype=src_tensor.dtype, device=src_tensor.device)
|
||||
slice_tensor = torch.narrow(padded_tensor, 0, 0, src_tensor.numel())
|
||||
slice_tensor.data.copy_(src_tensor.data)
|
||||
return padded_tensor
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,23 @@
|
||||
import torch
|
||||
from torch import nn
|
||||
from torch.nn import functional as F
|
||||
|
||||
|
||||
def fp32_layer_norm_forward(self, inputs: torch.Tensor) -> torch.Tensor:
|
||||
origin_dtype = inputs.dtype
|
||||
return F.layer_norm(inputs.float(), self.normalized_shape, self.weight.float() if self.weight is not None else None,
|
||||
self.bias.float() if self.bias is not None else None, self.eps).to(origin_dtype)
|
||||
|
||||
|
||||
def fp32_silu_forward(self, inputs: torch.Tensor) -> torch.Tensor:
|
||||
return torch.nn.functional.silu(inputs.float(), inplace=self.inplace).to(inputs.dtype)
|
||||
|
||||
|
||||
def fp32_gelu_forward(self, inputs: torch.Tensor) -> torch.Tensor:
|
||||
return torch.nn.functional.gelu(inputs.float(), approximate=self.approximate).to(inputs.dtype)
|
||||
|
||||
|
||||
def replace_with_fp32_forwards():
|
||||
nn.GELU.forward = fp32_gelu_forward
|
||||
nn.SiLU.forward = fp32_silu_forward
|
||||
nn.LayerNorm.forward = fp32_layer_norm_forward
|
||||
File diff suppressed because it is too large
Load Diff
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,31 @@
|
||||
import torch
|
||||
import os
|
||||
import torch.distributed as dist
|
||||
|
||||
|
||||
class ZPManager(object):
|
||||
def __init__(self, zp_size=8):
|
||||
self.rank = int(os.getenv('RANK', '0'))
|
||||
self.world_size = int(os.getenv("WORLD_SIZE", '1'))
|
||||
self.zp_size = zp_size
|
||||
self.zp_group = None
|
||||
self.zp_rank = None
|
||||
self.is_initialized = False
|
||||
|
||||
def init_group(self):
|
||||
if self.is_initialized:
|
||||
return
|
||||
|
||||
self.is_initialized = True
|
||||
|
||||
"""Initialize the sequence parallel group."""
|
||||
num_zp_groups: int = self.world_size // self.zp_size
|
||||
for i in range(num_zp_groups):
|
||||
ranks = range(i * self.zp_size, (i + 1) * self.zp_size)
|
||||
group = dist.new_group(ranks)
|
||||
if self.rank in ranks:
|
||||
self.zp_group = group
|
||||
self.zp_rank = self.rank % self.zp_size
|
||||
|
||||
|
||||
zp_manager = ZPManager()
|
||||
@@ -0,0 +1,92 @@
|
||||
from torchvision.transforms import Compose
|
||||
from transformers import AutoTokenizer, AutoImageProcessor
|
||||
|
||||
from torchvision import transforms
|
||||
from torchvision.transforms import Lambda
|
||||
|
||||
from opensora.dataset.t2v_datasets import T2V_dataset
|
||||
from opensora.dataset.inpaint_datasets import Inpaint_dataset
|
||||
from opensora.dataset.transform import ToTensorVideo, TemporalRandomCrop, RandomHorizontalFlipVideo, CenterCropResizeVideo, LongSideResizeVideo, SpatialStrideCropVideo
|
||||
from opensora.models.causalvideovae import ae_norm, ae_denorm
|
||||
|
||||
def getdataset(args):
|
||||
temporal_sample = TemporalRandomCrop(args.num_frames) # 16 x
|
||||
norm_fun = ae_norm[args.ae]
|
||||
resize_topcrop = [CenterCropResizeVideo((args.max_height, args.max_width), top_crop=True), ]
|
||||
resize = [CenterCropResizeVideo((args.max_height, args.max_width)), ]
|
||||
transform = transforms.Compose([
|
||||
ToTensorVideo(),
|
||||
*resize,
|
||||
# RandomHorizontalFlipVideo(p=0.5), # in case their caption have position decription
|
||||
norm_fun
|
||||
])
|
||||
transform_topcrop = transforms.Compose([
|
||||
ToTensorVideo(),
|
||||
*resize_topcrop,
|
||||
# RandomHorizontalFlipVideo(p=0.5), # in case their caption have position decription
|
||||
norm_fun
|
||||
])
|
||||
# tokenizer = AutoTokenizer.from_pretrained("/storage/ongoing/new/Open-Sora-Plan/cache_dir/mt5-xxl", cache_dir=args.cache_dir)
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.text_encoder_name, cache_dir=args.cache_dir)
|
||||
if args.dataset == 't2v':
|
||||
return T2V_dataset(args, transform=transform, temporal_sample=temporal_sample, tokenizer=tokenizer,
|
||||
transform_topcrop=transform_topcrop)
|
||||
elif args.dataset == 'inpaint' or args.dataset == 'i2v':
|
||||
return Inpaint_dataset(args, transform=transform, temporal_sample=temporal_sample, tokenizer=tokenizer,
|
||||
transform_topcrop=transform_topcrop)
|
||||
|
||||
raise NotImplementedError(args.dataset)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
from accelerate import Accelerator
|
||||
from opensora.dataset.t2v_datasets import dataset_prog
|
||||
import random
|
||||
from tqdm import tqdm
|
||||
args = type('args', (),
|
||||
{
|
||||
'ae': 'CausalVAEModel_4x8x8',
|
||||
'dataset': 't2v',
|
||||
'attention_mode': 'xformers',
|
||||
'use_rope': True,
|
||||
'model_max_length': 300,
|
||||
'max_height': 320,
|
||||
'max_width': 240,
|
||||
'num_frames': 1,
|
||||
'use_image_num': 0,
|
||||
'compress_kv_factor': 1,
|
||||
'interpolation_scale_t': 1,
|
||||
'interpolation_scale_h': 1,
|
||||
'interpolation_scale_w': 1,
|
||||
'cache_dir': '../cache_dir',
|
||||
'image_data': '/storage/ongoing/new/Open-Sora-Plan-bak/7.14bak/scripts/train_data/image_data.txt',
|
||||
'video_data': '1',
|
||||
'train_fps': 24,
|
||||
'drop_short_ratio': 1.0,
|
||||
'use_img_from_vid': False,
|
||||
'speed_factor': 1.0,
|
||||
'cfg': 0.1,
|
||||
'text_encoder_name': 'google/mt5-xxl',
|
||||
'dataloader_num_workers': 10,
|
||||
|
||||
}
|
||||
)
|
||||
accelerator = Accelerator()
|
||||
dataset = getdataset(args)
|
||||
num = len(dataset_prog.img_cap_list)
|
||||
zero = 0
|
||||
for idx in tqdm(range(num)):
|
||||
image_data = dataset_prog.img_cap_list[idx]
|
||||
caps = [i['cap'] if isinstance(i['cap'], list) else [i['cap']] for i in image_data]
|
||||
try:
|
||||
caps = [[random.choice(i)] for i in caps]
|
||||
except Exception as e:
|
||||
print(e)
|
||||
# import ipdb;ipdb.set_trace()
|
||||
print(image_data)
|
||||
zero += 1
|
||||
continue
|
||||
assert caps[0] is not None and len(caps[0]) > 0
|
||||
print(num, zero)
|
||||
import ipdb;ipdb.set_trace()
|
||||
print('end')
|
||||
@@ -0,0 +1,116 @@
|
||||
|
||||
import os, random
|
||||
import numpy as np
|
||||
|
||||
import torch
|
||||
from accelerate.logging import get_logger
|
||||
|
||||
from opensora.utils.utils import text_preprocessing
|
||||
|
||||
from opensora.dataset.t2v_datasets import SingletonMeta, DataSetProg
|
||||
from opensora.dataset.t2v_datasets import T2V_dataset
|
||||
|
||||
logger = get_logger(__name__)
|
||||
|
||||
dataset_prog = DataSetProg()
|
||||
|
||||
|
||||
class Meta_dataset(T2V_dataset):
|
||||
def __init__(self, args, transform, temporal_sample, tokenizer, transform_topcrop):
|
||||
super().__init__(args, transform, temporal_sample, tokenizer, transform_topcrop)
|
||||
|
||||
if self.num_frames != 1:
|
||||
# inpaint
|
||||
# The proportion of executing the i2v task.
|
||||
self.i2v_ratio = args.i2v_ratio
|
||||
self.transition_ratio = args.transition_ratio
|
||||
self.v2v_ratio = args.v2v_ratio
|
||||
self.clear_video_ratio = args.clear_video_ratio
|
||||
assert self.i2v_ratio + self.transition_ratio + self.v2v_ratio + self.clear_video_ratio < 1, 'The sum of i2v_ratio, transition_ratio, v2v_ratio and clear video ratio should be less than 1.'
|
||||
|
||||
self.default_text_ratio = args.default_text_ratio
|
||||
self.default_text = f"The {'video' if self.num_frames != 1 else 'image'} showcases a scene with coherent and clear visuals."
|
||||
|
||||
def get_mask_masked_video(self, video):
|
||||
# video shape (T, C, H, W)
|
||||
# 1 means masked, 0 means not masked
|
||||
t, c, h, w = video.shape
|
||||
mask = torch.ones_like(video, device=video.device, dtype=video.dtype)
|
||||
|
||||
rand_num = random.random()
|
||||
# i2v
|
||||
if rand_num < self.i2v_ratio:
|
||||
mask[0] = 0
|
||||
# transition
|
||||
elif rand_num < self.i2v_ratio + self.transition_ratio:
|
||||
mask[0] = 0
|
||||
mask[-1] = 0
|
||||
# video continuation
|
||||
elif rand_num < self.i2v_ratio + self.transition_ratio + self.v2v_ratio:
|
||||
end_idx = random.randint(1, t)
|
||||
mask[:end_idx] = 0
|
||||
# clear video
|
||||
elif rand_num < self.i2v_ratio + self.transition_ratio + self.v2v_ratio + self.clear_video_ratio:
|
||||
mask[:] = 0
|
||||
# random mask
|
||||
else:
|
||||
idx_to_select = random.randint(0, t - 1)
|
||||
selected_indices = random.sample(range(0, t), idx_to_select)
|
||||
mask[selected_indices] = 0
|
||||
masked_video = video * (mask < 0.5)
|
||||
|
||||
# save_video(masked_video.permute(0, 2, 3, 1).cpu().numpy(), 'masked_video.mp4')
|
||||
return dict(mask=mask, masked_video=masked_video)
|
||||
|
||||
def drop(self, text):
|
||||
rand_num = random.random()
|
||||
rand_num_text = random.random()
|
||||
|
||||
if rand_num < self.cfg:
|
||||
text = self.default_text if rand_num_text < self.default_text_ratio else ''
|
||||
|
||||
return dict(text=text)
|
||||
|
||||
|
||||
class Inpaint_dataset(Meta_dataset):
|
||||
def get_video(self, idx):
|
||||
video_path = dataset_prog.cap_list[idx]['path']
|
||||
assert os.path.exists(video_path), f"file {video_path} do not exist!"
|
||||
frame_indice = dataset_prog.cap_list[idx]['sample_frame_index']
|
||||
video = self.decord_read(video_path, predefine_num_frames=len(frame_indice))
|
||||
|
||||
h, w = video.shape[-2:]
|
||||
assert h / w <= 17 / 16 and h / w >= 8 / 16, f'Only videos with a ratio (h/w) less than 17/16 and more than 8/16 are supported. But video ({video_path}) found ratio is {round(h / w, 2)} with the shape of {video.shape}'
|
||||
t = video.shape[0]
|
||||
video = self.transform(video) # T C H W -> T C H W
|
||||
|
||||
# inpaint
|
||||
inpaint_cond_data = self.get_mask_masked_video(video)
|
||||
mask, masked_video = inpaint_cond_data['mask'], inpaint_cond_data['masked_video']
|
||||
video = torch.cat([video, masked_video, mask], dim=1) # T 3*C H W
|
||||
|
||||
# video = torch.rand(221, 3, 480, 640)
|
||||
|
||||
video = video.transpose(0, 1) # T C H W -> C T H W
|
||||
text = dataset_prog.cap_list[idx]['cap']
|
||||
if not isinstance(text, list):
|
||||
text = [text]
|
||||
text = [random.choice(text)]
|
||||
|
||||
text = text_preprocessing(text, support_Chinese=self.support_Chinese)
|
||||
|
||||
text = self.drop(text)['text']
|
||||
|
||||
text_tokens_and_mask = self.tokenizer(
|
||||
text,
|
||||
max_length=self.model_max_length,
|
||||
padding='max_length',
|
||||
truncation=True,
|
||||
return_attention_mask=True,
|
||||
add_special_tokens=True,
|
||||
return_tensors='pt'
|
||||
)
|
||||
input_ids = text_tokens_and_mask['input_ids']
|
||||
cond_mask = text_tokens_and_mask['attention_mask']
|
||||
return dict(pixel_values=video, input_ids=input_ids, cond_mask=cond_mask)
|
||||
|
||||
@@ -0,0 +1,422 @@
|
||||
import time
|
||||
import traceback
|
||||
|
||||
try:
|
||||
import torch_npu
|
||||
from opensora.npu_config import npu_config
|
||||
except:
|
||||
torch_npu = None
|
||||
npu_config = None
|
||||
import glob
|
||||
import json
|
||||
import os, io, csv, math, random
|
||||
import numpy as np
|
||||
import torchvision
|
||||
from einops import rearrange
|
||||
from decord import VideoReader
|
||||
from os.path import join as opj
|
||||
from collections import Counter
|
||||
|
||||
import torch
|
||||
import torchvision.transforms as transforms
|
||||
from torch.utils.data.dataset import Dataset
|
||||
from torch.utils.data import DataLoader, Dataset, get_worker_info
|
||||
from tqdm import tqdm
|
||||
from PIL import Image
|
||||
from accelerate.logging import get_logger
|
||||
|
||||
from opensora.utils.dataset_utils import DecordInit
|
||||
from opensora.utils.utils import text_preprocessing
|
||||
logger = get_logger(__name__)
|
||||
|
||||
def filter_json_by_existed_files(directory, data, postfixes=[".mp4", ".jpg"]):
|
||||
# 构建搜索模式,以匹配指定后缀的文件
|
||||
matching_files = []
|
||||
for postfix in postfixes:
|
||||
pattern = os.path.join(directory, '**', f'*{postfix}')
|
||||
matching_files.extend(glob.glob(pattern, recursive=True))
|
||||
|
||||
# 使用文件的绝对路径构建集合
|
||||
mp4_files_set = set(os.path.abspath(path) for path in matching_files)
|
||||
|
||||
# 过滤数据条目,只保留路径在mp4文件集合中的条目
|
||||
filtered_items = [item for item in data if item['path'] in mp4_files_set]
|
||||
|
||||
return filtered_items
|
||||
|
||||
|
||||
def random_video_noise(t, c, h, w):
|
||||
vid = torch.rand(t, c, h, w) * 255.0
|
||||
vid = vid.to(torch.uint8)
|
||||
return vid
|
||||
|
||||
|
||||
class SingletonMeta(type):
|
||||
"""
|
||||
这是一个元类,用于创建单例类。
|
||||
"""
|
||||
_instances = {}
|
||||
|
||||
def __call__(cls, *args, **kwargs):
|
||||
if cls not in cls._instances:
|
||||
instance = super().__call__(*args, **kwargs)
|
||||
cls._instances[cls] = instance
|
||||
return cls._instances[cls]
|
||||
|
||||
|
||||
class DataSetProg(metaclass=SingletonMeta):
|
||||
def __init__(self):
|
||||
self.cap_list = []
|
||||
self.elements = []
|
||||
self.num_workers = 1
|
||||
self.n_elements = 0
|
||||
self.worker_elements = dict()
|
||||
self.n_used_elements = dict()
|
||||
|
||||
def set_cap_list(self, num_workers, cap_list, n_elements):
|
||||
self.num_workers = num_workers
|
||||
self.cap_list = cap_list
|
||||
self.n_elements = n_elements
|
||||
self.elements = list(range(n_elements))
|
||||
random.shuffle(self.elements)
|
||||
print(f"n_elements: {len(self.elements)}", flush=True)
|
||||
|
||||
for i in range(self.num_workers):
|
||||
self.n_used_elements[i] = 0
|
||||
per_worker = int(math.ceil(len(self.elements) / float(self.num_workers)))
|
||||
start = i * per_worker
|
||||
end = min(start + per_worker, len(self.elements))
|
||||
self.worker_elements[i] = self.elements[start: end]
|
||||
|
||||
def get_item(self, work_info):
|
||||
if work_info is None:
|
||||
worker_id = 0
|
||||
else:
|
||||
worker_id = work_info.id
|
||||
|
||||
idx = self.worker_elements[worker_id][self.n_used_elements[worker_id] % len(self.worker_elements[worker_id])]
|
||||
self.n_used_elements[worker_id] += 1
|
||||
return idx
|
||||
|
||||
|
||||
dataset_prog = DataSetProg()
|
||||
|
||||
def find_closest_y(x, vae_stride_t=4, model_ds_t=4):
|
||||
if x < 29:
|
||||
return -1
|
||||
for y in range(x, 12, -1):
|
||||
if (y - 1) % vae_stride_t == 0 and ((y - 1) // vae_stride_t + 1) % model_ds_t == 0:
|
||||
# 4, 8: y in [29, 61, 93, 125, 157, 189, 221, 253, 285, 317, 349, 381, 413, 445, 477, 509, ...]
|
||||
# 4, 4: y in [29, 45, 61, 77, 93, 109, 125, 141, 157, 173, 189, 205, 221, 237, 253, 269, 285, 301, 317, 333, 349, 365, 381, 397, 413, 429, 445, 461, 477, 493, 509, ...]
|
||||
return y
|
||||
return -1
|
||||
|
||||
def filter_resolution(h, w, max_h_div_w_ratio=17/16, min_h_div_w_ratio=8 / 16):
|
||||
if h / w <= max_h_div_w_ratio and h / w >= min_h_div_w_ratio:
|
||||
return True
|
||||
return False
|
||||
|
||||
|
||||
|
||||
class T2V_dataset(Dataset):
|
||||
def __init__(self, args, transform, temporal_sample, tokenizer, transform_topcrop):
|
||||
self.data = args.data
|
||||
self.num_frames = args.num_frames
|
||||
self.train_fps = args.train_fps
|
||||
self.use_image_num = args.use_image_num
|
||||
self.use_img_from_vid = args.use_img_from_vid
|
||||
self.transform = transform
|
||||
self.transform_topcrop = transform_topcrop
|
||||
self.temporal_sample = temporal_sample
|
||||
self.tokenizer = tokenizer
|
||||
self.model_max_length = args.model_max_length
|
||||
self.cfg = args.cfg
|
||||
self.speed_factor = args.speed_factor
|
||||
self.max_height = args.max_height
|
||||
self.max_width = args.max_width
|
||||
self.drop_short_ratio = args.drop_short_ratio
|
||||
assert self.speed_factor >= 1
|
||||
self.v_decoder = DecordInit()
|
||||
|
||||
self.support_Chinese = True
|
||||
if not ('mt5' in args.text_encoder_name):
|
||||
self.support_Chinese = False
|
||||
|
||||
cap_list = self.get_cap_list()
|
||||
|
||||
assert len(cap_list) > 0
|
||||
cap_list, self.sample_num_frames = self.define_frame_index(cap_list)
|
||||
self.lengths = self.sample_num_frames
|
||||
|
||||
n_elements = len(cap_list)
|
||||
dataset_prog.set_cap_list(args.dataloader_num_workers, cap_list, n_elements)
|
||||
|
||||
print(f"video length: {len(dataset_prog.cap_list)}", flush=True)
|
||||
|
||||
def set_checkpoint(self, n_used_elements):
|
||||
for i in range(len(dataset_prog.n_used_elements)):
|
||||
dataset_prog.n_used_elements[i] = n_used_elements
|
||||
|
||||
def __len__(self):
|
||||
return dataset_prog.n_elements
|
||||
|
||||
def __getitem__(self, idx):
|
||||
try:
|
||||
data = self.get_data(idx)
|
||||
return data
|
||||
except Exception as e:
|
||||
logger.info(f'Error with {e}')
|
||||
# 打印异常堆栈
|
||||
if idx in dataset_prog.cap_list:
|
||||
logger.info(f"Caught an exception! {dataset_prog.cap_list[idx]}")
|
||||
# traceback.print_exc()
|
||||
# traceback.print_stack()
|
||||
return self.__getitem__(random.randint(0, self.__len__() - 1))
|
||||
|
||||
def get_data(self, idx):
|
||||
path = dataset_prog.cap_list[idx]['path']
|
||||
if path.endswith('.mp4'):
|
||||
return self.get_video(idx)
|
||||
else:
|
||||
return self.get_image(idx)
|
||||
|
||||
def get_video(self, idx):
|
||||
# npu_config.print_msg(f"current idx is {idx}")
|
||||
# video = random.choice([random_video_noise(65, 3, 336, 448), random_video_noise(65, 3, 1024, 1024), random_video_noise(65, 3, 360, 480)])
|
||||
# # print('random shape', video.shape)
|
||||
# input_ids = torch.ones(1, 120).to(torch.long).squeeze(0)
|
||||
# cond_mask = torch.cat([torch.ones(1, 60).to(torch.long), torch.ones(1, 60).to(torch.long)], dim=1).squeeze(0)
|
||||
|
||||
video_path = dataset_prog.cap_list[idx]['path']
|
||||
assert os.path.exists(video_path), f"file {video_path} do not exist!"
|
||||
frame_indice = dataset_prog.cap_list[idx]['sample_frame_index']
|
||||
video = self.decord_read(video_path, predefine_num_frames=len(frame_indice))
|
||||
|
||||
h, w = video.shape[-2:]
|
||||
assert h / w <= 17 / 16 and h / w >= 8 / 16, f'Only videos with a ratio (h/w) less than 17/16 and more than 8/16 are supported. But video ({video_path}) found ratio is {round(h / w, 2)} with the shape of {video.shape}'
|
||||
t = video.shape[0]
|
||||
video = self.transform(video) # T C H W -> T C H W
|
||||
|
||||
# video = torch.rand(221, 3, 480, 640)
|
||||
|
||||
video = video.transpose(0, 1) # T C H W -> C T H W
|
||||
text = dataset_prog.cap_list[idx]['cap']
|
||||
if not isinstance(text, list):
|
||||
text = [text]
|
||||
text = [random.choice(text)]
|
||||
|
||||
text = text_preprocessing(text, support_Chinese=self.support_Chinese) if random.random() > self.cfg else ""
|
||||
text_tokens_and_mask = self.tokenizer(
|
||||
text,
|
||||
max_length=self.model_max_length,
|
||||
padding='max_length',
|
||||
truncation=True,
|
||||
return_attention_mask=True,
|
||||
add_special_tokens=True,
|
||||
return_tensors='pt'
|
||||
)
|
||||
input_ids = text_tokens_and_mask['input_ids']
|
||||
cond_mask = text_tokens_and_mask['attention_mask']
|
||||
return dict(pixel_values=video, input_ids=input_ids, cond_mask=cond_mask)
|
||||
|
||||
def get_image(self, idx):
|
||||
image_data = dataset_prog.cap_list[idx] # [{'path': path, 'cap': cap}, ...]
|
||||
|
||||
# import ipdb;ipdb.set_trace()
|
||||
image = Image.open(image_data['path']).convert('RGB') # [h, w, c]
|
||||
image = torch.from_numpy(np.array(image)) # [h, w, c]
|
||||
image = rearrange(image, 'h w c -> c h w').unsqueeze(0) # [1 c h w]
|
||||
# for i in image:
|
||||
# h, w = i.shape[-2:]
|
||||
# assert h / w <= 17 / 16 and h / w >= 8 / 16, f'Only image with a ratio (h/w) less than 17/16 and more than 8/16 are supported. But found ratio is {round(h / w, 2)} with the shape of {i.shape}'
|
||||
|
||||
image = self.transform_topcrop(image) if 'human_images' in image_data['path'] else self.transform(image) # [1 C H W] -> num_img [1 C H W]
|
||||
|
||||
# image = [torch.rand(1, 3, 480, 640) for i in image_data]
|
||||
image = image.transpose(0, 1) # [1 C H W] -> [C 1 H W]
|
||||
|
||||
caps = image_data['cap'] if isinstance(image_data['cap'], list) else [image_data['cap']]
|
||||
caps = [random.choice(caps)]
|
||||
text = text_preprocessing(caps, support_Chinese=self.support_Chinese)
|
||||
input_ids, cond_mask = [], []
|
||||
text = text if random.random() > self.cfg else ""
|
||||
text_tokens_and_mask = self.tokenizer(
|
||||
text,
|
||||
max_length=self.model_max_length,
|
||||
padding='max_length',
|
||||
truncation=True,
|
||||
return_attention_mask=True,
|
||||
add_special_tokens=True,
|
||||
return_tensors='pt'
|
||||
)
|
||||
input_ids = text_tokens_and_mask['input_ids'] # 1, l
|
||||
cond_mask = text_tokens_and_mask['attention_mask'] # 1, l
|
||||
return dict(pixel_values=image, input_ids=input_ids, cond_mask=cond_mask)
|
||||
|
||||
def define_frame_index(self, cap_list):
|
||||
|
||||
new_cap_list = []
|
||||
sample_num_frames = []
|
||||
cnt_too_long = 0
|
||||
cnt_too_short = 0
|
||||
cnt_no_cap = 0
|
||||
cnt_no_resolution = 0
|
||||
cnt_resolution_mismatch = 0
|
||||
cnt_movie = 0
|
||||
cnt_img = 0
|
||||
for i in cap_list:
|
||||
path = i['path']
|
||||
cap = i.get('cap', None)
|
||||
# ======no caption=====
|
||||
if cap is None:
|
||||
cnt_no_cap += 1
|
||||
continue
|
||||
if path.endswith('.mp4'):
|
||||
# ======no fps and duration=====
|
||||
duration = i.get('duration', None)
|
||||
fps = i.get('fps', None)
|
||||
if fps is None or duration is None:
|
||||
continue
|
||||
|
||||
# ======resolution mismatch=====
|
||||
resolution = i.get('resolution', None)
|
||||
if resolution is None:
|
||||
cnt_no_resolution += 1
|
||||
continue
|
||||
else:
|
||||
if resolution.get('height', None) is None or resolution.get('width', None) is None:
|
||||
cnt_no_resolution += 1
|
||||
continue
|
||||
height, width = i['resolution']['height'], i['resolution']['width']
|
||||
aspect = self.max_height / self.max_width
|
||||
hw_aspect_thr = 1.5
|
||||
is_pick = filter_resolution(height, width, max_h_div_w_ratio=hw_aspect_thr*aspect,
|
||||
min_h_div_w_ratio=1/hw_aspect_thr*aspect)
|
||||
if not is_pick:
|
||||
cnt_resolution_mismatch += 1
|
||||
continue
|
||||
|
||||
# # ignore image resolution mismatch
|
||||
# if self.max_height > resolution['height'] or self.max_width > resolution['width']:
|
||||
# cnt_resolution_mismatch += 1
|
||||
# continue
|
||||
|
||||
# import ipdb;ipdb.set_trace()
|
||||
i['num_frames'] = int(fps * duration)
|
||||
# max 5.0 and min 1.0 are just thresholds to filter some videos which have suitable duration.
|
||||
if i['num_frames'] > 2.0 * (self.num_frames * fps / self.train_fps * self.speed_factor): # too long video is not suitable for this training stage (self.num_frames)
|
||||
cnt_too_long += 1
|
||||
continue
|
||||
# if i['num_frames'] < 1.0/1 * (self.num_frames * fps / self.train_fps * self.speed_factor): # too short video is not suitable for this training stage
|
||||
# cnt_too_short += 1
|
||||
# continue
|
||||
|
||||
# resample in case high fps, such as 50/60/90/144 -> train_fps(e.g, 24)
|
||||
frame_interval = fps / self.train_fps
|
||||
start_frame_idx = 0
|
||||
frame_indices = np.arange(start_frame_idx, i['num_frames'], frame_interval).astype(int)
|
||||
frame_indices = frame_indices[frame_indices < i['num_frames']]
|
||||
|
||||
# comment out it to enable dynamic frames training
|
||||
if len(frame_indices) < self.num_frames and random.random() < self.drop_short_ratio:
|
||||
cnt_too_short += 1
|
||||
continue
|
||||
|
||||
# too long video will be temporal-crop randomly
|
||||
if len(frame_indices) > self.num_frames:
|
||||
begin_index, end_index = self.temporal_sample(len(frame_indices))
|
||||
frame_indices = frame_indices[begin_index: end_index]
|
||||
# frame_indices = frame_indices[:self.num_frames] # head crop
|
||||
# to find a suitable end_frame_idx, to ensure we do not need pad video
|
||||
end_frame_idx = find_closest_y(len(frame_indices), vae_stride_t=4, model_ds_t=4)
|
||||
if end_frame_idx == -1: # too short that can not be encoded exactly by videovae
|
||||
cnt_too_short += 1
|
||||
continue
|
||||
frame_indices = frame_indices[:end_frame_idx]
|
||||
|
||||
i['sample_frame_index'] = frame_indices.tolist()
|
||||
new_cap_list.append(i)
|
||||
i['sample_num_frames'] = len(i['sample_frame_index']) # will use in dataloader(group sampler)
|
||||
sample_num_frames.append(i['sample_num_frames'])
|
||||
elif path.endswith('.jpg'): # image
|
||||
cnt_img += 1
|
||||
new_cap_list.append(i)
|
||||
i['sample_num_frames'] = 1
|
||||
sample_num_frames.append(i['sample_num_frames'])
|
||||
else:
|
||||
raise NameError(f"Unknown file extention {path.split('.')[-1]}, only support .mp4 for video and .jpg for image")
|
||||
# import ipdb;ipdb.set_trace()
|
||||
logger.info(f'no_cap: {cnt_no_cap}, too_long: {cnt_too_long}, too_short: {cnt_too_short}, '
|
||||
f'no_resolution: {cnt_no_resolution}, resolution_mismatch: {cnt_resolution_mismatch}, '
|
||||
f'Counter(sample_num_frames): {Counter(sample_num_frames)}, cnt_movie: {cnt_movie}, cnt_img: {cnt_img}, '
|
||||
f'before filter: {len(cap_list)}, after filter: {len(new_cap_list)}')
|
||||
return new_cap_list, sample_num_frames
|
||||
|
||||
def decord_read(self, path, predefine_num_frames):
|
||||
decord_vr = self.v_decoder(path)
|
||||
total_frames = len(decord_vr)
|
||||
fps = decord_vr.get_avg_fps() if decord_vr.get_avg_fps() > 0 else 30.0
|
||||
# import ipdb;ipdb.set_trace()
|
||||
# resample in case high fps, such as 50/60/90/144 -> train_fps(e.g, 24)
|
||||
frame_interval = 1.0 if abs(fps - self.train_fps) < 0.1 else fps / self.train_fps
|
||||
start_frame_idx = 0
|
||||
frame_indices = np.arange(start_frame_idx, total_frames, frame_interval).astype(int)
|
||||
frame_indices = frame_indices[frame_indices < total_frames]
|
||||
#import ipdb;ipdb.set_trace()
|
||||
# speed up
|
||||
max_speed_factor = len(frame_indices) / self.num_frames
|
||||
if self.speed_factor > 1 and max_speed_factor > 1:
|
||||
# speed_factor = random.uniform(1.0, min(self.speed_factor, max_speed_factor))
|
||||
speed_factor = min(self.speed_factor, max_speed_factor)
|
||||
target_frame_count = int(len(frame_indices) / speed_factor)
|
||||
speed_frame_idx = np.linspace(0, len(frame_indices) - 1, target_frame_count, dtype=int)
|
||||
frame_indices = frame_indices[speed_frame_idx]
|
||||
|
||||
# too long video will be temporal-crop randomly
|
||||
if len(frame_indices) > self.num_frames:
|
||||
begin_index, end_index = self.temporal_sample(len(frame_indices))
|
||||
frame_indices = frame_indices[begin_index: end_index]
|
||||
# frame_indices = frame_indices[:self.num_frames] # head crop
|
||||
|
||||
# to find a suitable end_frame_idx, to ensure we do not need pad video
|
||||
end_frame_idx = find_closest_y(len(frame_indices), vae_stride_t=4, model_ds_t=4)
|
||||
if end_frame_idx == -1: # too short that can not be encoded exactly by videovae
|
||||
raise IndexError(f'video ({path}) has {total_frames} frames, but need to sample {len(frame_indices)} frames ({frame_indices})')
|
||||
frame_indices = frame_indices[:end_frame_idx]
|
||||
if predefine_num_frames != len(frame_indices):
|
||||
raise ValueError(f'predefine_num_frames ({predefine_num_frames}) is not equal with frame_indices ({len(frame_indices)})')
|
||||
if len(frame_indices) < self.num_frames and self.drop_short_ratio >= 1:
|
||||
raise IndexError(f'video ({path}) has {total_frames} frames, but need to sample {len(frame_indices)} frames ({frame_indices})')
|
||||
video_data = decord_vr.get_batch(frame_indices).asnumpy()
|
||||
video_data = torch.from_numpy(video_data)
|
||||
video_data = video_data.permute(0, 3, 1, 2) # (T, H, W, C) -> (T C H W)
|
||||
return video_data
|
||||
|
||||
def read_jsons(self, data):
|
||||
cap_lists = []
|
||||
with open(data, 'r') as f:
|
||||
folder_anno = [i.strip().split(',') for i in f.readlines() if len(i.strip()) > 0]
|
||||
for folder, anno in folder_anno:
|
||||
with open(anno, 'r') as f:
|
||||
sub_list = json.load(f)
|
||||
logger.info(f'Building {anno}...')
|
||||
for i in range(len(sub_list)):
|
||||
sub_list[i]['path'] = opj(folder, sub_list[i]['path'])
|
||||
cap_lists += sub_list
|
||||
return cap_lists
|
||||
|
||||
# def get_img_cap_list(self):
|
||||
# use_image_num = self.use_image_num if self.use_image_num != 0 else 1
|
||||
# if npu_config is None:
|
||||
# img_cap_lists = self.read_jsons(self.image_data, postfix=".jpg")
|
||||
# img_cap_lists = [img_cap_lists[i: i + use_image_num] for i in range(0, len(img_cap_lists), use_image_num)]
|
||||
# else:
|
||||
# img_cap_lists = npu_config.try_load_pickle("img_cap_lists_all",
|
||||
# lambda: self.read_jsons(self.image_data, postfix=".jpg"))
|
||||
# img_cap_lists = [img_cap_lists[i: i + use_image_num] for i in range(0, len(img_cap_lists), use_image_num)]
|
||||
# img_cap_lists = img_cap_lists[npu_config.get_local_rank()::npu_config.N_NPU_PER_NODE]
|
||||
# return img_cap_lists[:-1] # drop last to avoid error length
|
||||
|
||||
def get_cap_list(self):
|
||||
cap_lists = self.read_jsons(self.data)
|
||||
return cap_lists
|
||||
@@ -0,0 +1,592 @@
|
||||
import torch
|
||||
import random
|
||||
import numbers
|
||||
from torchvision.transforms import RandomCrop, RandomResizedCrop
|
||||
|
||||
|
||||
def _is_tensor_video_clip(clip):
|
||||
if not torch.is_tensor(clip):
|
||||
raise TypeError("clip should be Tensor. Got %s" % type(clip))
|
||||
|
||||
if not clip.ndimension() == 4:
|
||||
raise ValueError("clip should be 4D. Got %dD" % clip.dim())
|
||||
|
||||
return True
|
||||
|
||||
|
||||
def center_crop_arr(pil_image, image_size):
|
||||
"""
|
||||
Center cropping implementation from ADM.
|
||||
https://github.com/openai/guided-diffusion/blob/8fb3ad9197f16bbc40620447b2742e13458d2831/guided_diffusion/image_datasets.py#L126
|
||||
"""
|
||||
while min(*pil_image.size) >= 2 * image_size:
|
||||
pil_image = pil_image.resize(
|
||||
tuple(x // 2 for x in pil_image.size), resample=Image.BOX
|
||||
)
|
||||
|
||||
scale = image_size / min(*pil_image.size)
|
||||
pil_image = pil_image.resize(
|
||||
tuple(round(x * scale) for x in pil_image.size), resample=Image.BICUBIC
|
||||
)
|
||||
|
||||
arr = np.array(pil_image)
|
||||
crop_y = (arr.shape[0] - image_size) // 2
|
||||
crop_x = (arr.shape[1] - image_size) // 2
|
||||
return Image.fromarray(arr[crop_y: crop_y + image_size, crop_x: crop_x + image_size])
|
||||
|
||||
|
||||
def crop(clip, i, j, h, w):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
"""
|
||||
if len(clip.size()) != 4:
|
||||
raise ValueError("clip should be a 4D tensor")
|
||||
return clip[..., i: i + h, j: j + w]
|
||||
|
||||
|
||||
def resize(clip, target_size, interpolation_mode):
|
||||
if len(target_size) != 2:
|
||||
raise ValueError(f"target size should be tuple (height, width), instead got {target_size}")
|
||||
return torch.nn.functional.interpolate(clip, size=target_size, mode=interpolation_mode, align_corners=True, antialias=True)
|
||||
|
||||
|
||||
def resize_scale(clip, target_size, interpolation_mode):
|
||||
if len(target_size) != 2:
|
||||
raise ValueError(f"target size should be tuple (height, width), instead got {target_size}")
|
||||
H, W = clip.size(-2), clip.size(-1)
|
||||
scale_ = target_size[0] / min(H, W)
|
||||
return torch.nn.functional.interpolate(clip, scale_factor=scale_, mode=interpolation_mode, align_corners=True, antialias=True)
|
||||
|
||||
|
||||
def resized_crop(clip, i, j, h, w, size, interpolation_mode="bilinear"):
|
||||
"""
|
||||
Do spatial cropping and resizing to the video clip
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
i (int): i in (i,j) i.e coordinates of the upper left corner.
|
||||
j (int): j in (i,j) i.e coordinates of the upper left corner.
|
||||
h (int): Height of the cropped region.
|
||||
w (int): Width of the cropped region.
|
||||
size (tuple(int, int)): height and width of resized clip
|
||||
Returns:
|
||||
clip (torch.tensor): Resized and cropped clip. Size is (T, C, H, W)
|
||||
"""
|
||||
if not _is_tensor_video_clip(clip):
|
||||
raise ValueError("clip should be a 4D torch.tensor")
|
||||
clip = crop(clip, i, j, h, w)
|
||||
clip = resize(clip, size, interpolation_mode)
|
||||
return clip
|
||||
|
||||
|
||||
def center_crop(clip, crop_size):
|
||||
if not _is_tensor_video_clip(clip):
|
||||
raise ValueError("clip should be a 4D torch.tensor")
|
||||
h, w = clip.size(-2), clip.size(-1)
|
||||
th, tw = crop_size
|
||||
if h < th or w < tw:
|
||||
raise ValueError("height and width must be no smaller than crop_size")
|
||||
|
||||
i = int(round((h - th) / 2.0))
|
||||
j = int(round((w - tw) / 2.0))
|
||||
return crop(clip, i, j, th, tw)
|
||||
|
||||
|
||||
def center_crop_using_short_edge(clip):
|
||||
if not _is_tensor_video_clip(clip):
|
||||
raise ValueError("clip should be a 4D torch.tensor")
|
||||
h, w = clip.size(-2), clip.size(-1)
|
||||
if h < w:
|
||||
th, tw = h, h
|
||||
i = 0
|
||||
j = int(round((w - tw) / 2.0))
|
||||
else:
|
||||
th, tw = w, w
|
||||
i = int(round((h - th) / 2.0))
|
||||
j = 0
|
||||
return crop(clip, i, j, th, tw)
|
||||
|
||||
|
||||
|
||||
def center_crop_th_tw(clip, th, tw, top_crop):
|
||||
if not _is_tensor_video_clip(clip):
|
||||
raise ValueError("clip should be a 4D torch.tensor")
|
||||
|
||||
# import ipdb;ipdb.set_trace()
|
||||
h, w = clip.size(-2), clip.size(-1)
|
||||
tr = th / tw
|
||||
if h / w > tr:
|
||||
new_h = int(w * tr)
|
||||
new_w = w
|
||||
else:
|
||||
new_h = h
|
||||
new_w = int(h / tr)
|
||||
|
||||
i = 0 if top_crop else int(round((h - new_h) / 2.0))
|
||||
j = int(round((w - new_w) / 2.0))
|
||||
return crop(clip, i, j, new_h, new_w)
|
||||
|
||||
def random_shift_crop(clip):
|
||||
'''
|
||||
Slide along the long edge, with the short edge as crop size
|
||||
'''
|
||||
if not _is_tensor_video_clip(clip):
|
||||
raise ValueError("clip should be a 4D torch.tensor")
|
||||
h, w = clip.size(-2), clip.size(-1)
|
||||
|
||||
if h <= w:
|
||||
long_edge = w
|
||||
short_edge = h
|
||||
else:
|
||||
long_edge = h
|
||||
short_edge = w
|
||||
|
||||
th, tw = short_edge, short_edge
|
||||
|
||||
i = torch.randint(0, h - th + 1, size=(1,)).item()
|
||||
j = torch.randint(0, w - tw + 1, size=(1,)).item()
|
||||
return crop(clip, i, j, th, tw)
|
||||
|
||||
|
||||
def to_tensor(clip):
|
||||
"""
|
||||
Convert tensor data type from uint8 to float, divide value by 255.0 and
|
||||
permute the dimensions of clip tensor
|
||||
Args:
|
||||
clip (torch.tensor, dtype=torch.uint8): Size is (T, C, H, W)
|
||||
Return:
|
||||
clip (torch.tensor, dtype=torch.float): Size is (T, C, H, W)
|
||||
"""
|
||||
_is_tensor_video_clip(clip)
|
||||
if not clip.dtype == torch.uint8:
|
||||
raise TypeError("clip tensor should have data type uint8. Got %s" % str(clip.dtype))
|
||||
# return clip.float().permute(3, 0, 1, 2) / 255.0
|
||||
return clip.float() / 255.0
|
||||
|
||||
|
||||
def normalize(clip, mean, std, inplace=False):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be normalized. Size is (T, C, H, W)
|
||||
mean (tuple): pixel RGB mean. Size is (3)
|
||||
std (tuple): pixel standard deviation. Size is (3)
|
||||
Returns:
|
||||
normalized clip (torch.tensor): Size is (T, C, H, W)
|
||||
"""
|
||||
if not _is_tensor_video_clip(clip):
|
||||
raise ValueError("clip should be a 4D torch.tensor")
|
||||
if not inplace:
|
||||
clip = clip.clone()
|
||||
mean = torch.as_tensor(mean, dtype=clip.dtype, device=clip.device)
|
||||
# print(mean)
|
||||
std = torch.as_tensor(std, dtype=clip.dtype, device=clip.device)
|
||||
clip.sub_(mean[:, None, None, None]).div_(std[:, None, None, None])
|
||||
return clip
|
||||
|
||||
|
||||
def hflip(clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be normalized. Size is (T, C, H, W)
|
||||
Returns:
|
||||
flipped clip (torch.tensor): Size is (T, C, H, W)
|
||||
"""
|
||||
if not _is_tensor_video_clip(clip):
|
||||
raise ValueError("clip should be a 4D torch.tensor")
|
||||
return clip.flip(-1)
|
||||
|
||||
|
||||
class RandomCropVideo:
|
||||
def __init__(self, size):
|
||||
if isinstance(size, numbers.Number):
|
||||
self.size = (int(size), int(size))
|
||||
else:
|
||||
self.size = size
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
Returns:
|
||||
torch.tensor: randomly cropped video clip.
|
||||
size is (T, C, OH, OW)
|
||||
"""
|
||||
i, j, h, w = self.get_params(clip)
|
||||
return crop(clip, i, j, h, w)
|
||||
|
||||
def get_params(self, clip):
|
||||
h, w = clip.shape[-2:]
|
||||
th, tw = self.size
|
||||
|
||||
if h < th or w < tw:
|
||||
raise ValueError(f"Required crop size {(th, tw)} is larger than input image size {(h, w)}")
|
||||
|
||||
if w == tw and h == th:
|
||||
return 0, 0, h, w
|
||||
|
||||
i = torch.randint(0, h - th + 1, size=(1,)).item()
|
||||
j = torch.randint(0, w - tw + 1, size=(1,)).item()
|
||||
|
||||
return i, j, th, tw
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(size={self.size})"
|
||||
|
||||
|
||||
class SpatialStrideCropVideo:
|
||||
def __init__(self, stride):
|
||||
self.stride = stride
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
Returns:
|
||||
torch.tensor: cropped video clip by stride.
|
||||
size is (T, C, OH, OW)
|
||||
"""
|
||||
i, j, h, w = self.get_params(clip)
|
||||
return crop(clip, i, j, h, w)
|
||||
|
||||
def get_params(self, clip):
|
||||
h, w = clip.shape[-2:]
|
||||
|
||||
th, tw = h // self.stride * self.stride, w // self.stride * self.stride
|
||||
|
||||
return 0, 0, th, tw # from top-left
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(size={self.size})"
|
||||
|
||||
class LongSideResizeVideo:
|
||||
'''
|
||||
First use the long side,
|
||||
then resize to the specified size
|
||||
'''
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
size,
|
||||
skip_low_resolution=False,
|
||||
interpolation_mode="bilinear",
|
||||
):
|
||||
self.size = size
|
||||
self.skip_low_resolution = skip_low_resolution
|
||||
self.interpolation_mode = interpolation_mode
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
Returns:
|
||||
torch.tensor: scale resized video clip.
|
||||
size is (T, C, 512, *) or (T, C, *, 512)
|
||||
"""
|
||||
_, _, h, w = clip.shape
|
||||
if self.skip_low_resolution and max(h, w) <= self.size:
|
||||
return clip
|
||||
if h > w:
|
||||
w = int(w * self.size / h)
|
||||
h = self.size
|
||||
else:
|
||||
h = int(h * self.size / w)
|
||||
w = self.size
|
||||
resize_clip = resize(clip, target_size=(h, w),
|
||||
interpolation_mode=self.interpolation_mode)
|
||||
return resize_clip
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(size={self.size}, interpolation_mode={self.interpolation_mode}"
|
||||
|
||||
class CenterCropResizeVideo:
|
||||
'''
|
||||
First use the short side for cropping length,
|
||||
center crop video, then resize to the specified size
|
||||
'''
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
size,
|
||||
top_crop=False,
|
||||
interpolation_mode="bilinear",
|
||||
):
|
||||
if len(size) != 2:
|
||||
raise ValueError(f"size should be tuple (height, width), instead got {size}")
|
||||
self.size = size
|
||||
self.top_crop = top_crop
|
||||
self.interpolation_mode = interpolation_mode
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
Returns:
|
||||
torch.tensor: scale resized / center cropped video clip.
|
||||
size is (T, C, crop_size, crop_size)
|
||||
"""
|
||||
# clip_center_crop = center_crop_using_short_edge(clip)
|
||||
clip_center_crop = center_crop_th_tw(clip, self.size[0], self.size[1], top_crop=self.top_crop)
|
||||
# import ipdb;ipdb.set_trace()
|
||||
clip_center_crop_resize = resize(clip_center_crop, target_size=self.size,
|
||||
interpolation_mode=self.interpolation_mode)
|
||||
return clip_center_crop_resize
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(size={self.size}, interpolation_mode={self.interpolation_mode}"
|
||||
|
||||
|
||||
class UCFCenterCropVideo:
|
||||
'''
|
||||
First scale to the specified size in equal proportion to the short edge,
|
||||
then center cropping
|
||||
'''
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
size,
|
||||
interpolation_mode="bilinear",
|
||||
):
|
||||
if isinstance(size, tuple):
|
||||
if len(size) != 2:
|
||||
raise ValueError(f"size should be tuple (height, width), instead got {size}")
|
||||
self.size = size
|
||||
else:
|
||||
self.size = (size, size)
|
||||
|
||||
self.interpolation_mode = interpolation_mode
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
Returns:
|
||||
torch.tensor: scale resized / center cropped video clip.
|
||||
size is (T, C, crop_size, crop_size)
|
||||
"""
|
||||
clip_resize = resize_scale(clip=clip, target_size=self.size, interpolation_mode=self.interpolation_mode)
|
||||
clip_center_crop = center_crop(clip_resize, self.size)
|
||||
return clip_center_crop
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(size={self.size}, interpolation_mode={self.interpolation_mode}"
|
||||
|
||||
|
||||
class KineticsRandomCropResizeVideo:
|
||||
'''
|
||||
Slide along the long edge, with the short edge as crop size. And resie to the desired size.
|
||||
'''
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
size,
|
||||
interpolation_mode="bilinear",
|
||||
):
|
||||
if isinstance(size, tuple):
|
||||
if len(size) != 2:
|
||||
raise ValueError(f"size should be tuple (height, width), instead got {size}")
|
||||
self.size = size
|
||||
else:
|
||||
self.size = (size, size)
|
||||
|
||||
self.interpolation_mode = interpolation_mode
|
||||
|
||||
def __call__(self, clip):
|
||||
clip_random_crop = random_shift_crop(clip)
|
||||
clip_resize = resize(clip_random_crop, self.size, self.interpolation_mode)
|
||||
return clip_resize
|
||||
|
||||
|
||||
class CenterCropVideo:
|
||||
def __init__(
|
||||
self,
|
||||
size,
|
||||
interpolation_mode="bilinear",
|
||||
):
|
||||
if isinstance(size, tuple):
|
||||
if len(size) != 2:
|
||||
raise ValueError(f"size should be tuple (height, width), instead got {size}")
|
||||
self.size = size
|
||||
else:
|
||||
self.size = (size, size)
|
||||
|
||||
self.interpolation_mode = interpolation_mode
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
Returns:
|
||||
torch.tensor: center cropped video clip.
|
||||
size is (T, C, crop_size, crop_size)
|
||||
"""
|
||||
clip_center_crop = center_crop(clip, self.size)
|
||||
return clip_center_crop
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(size={self.size}, interpolation_mode={self.interpolation_mode}"
|
||||
|
||||
|
||||
class NormalizeVideo:
|
||||
"""
|
||||
Normalize the video clip by mean subtraction and division by standard deviation
|
||||
Args:
|
||||
mean (3-tuple): pixel RGB mean
|
||||
std (3-tuple): pixel RGB standard deviation
|
||||
inplace (boolean): whether do in-place normalization
|
||||
"""
|
||||
|
||||
def __init__(self, mean, std, inplace=False):
|
||||
self.mean = mean
|
||||
self.std = std
|
||||
self.inplace = inplace
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): video clip must be normalized. Size is (C, T, H, W)
|
||||
"""
|
||||
return normalize(clip, self.mean, self.std, self.inplace)
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(mean={self.mean}, std={self.std}, inplace={self.inplace})"
|
||||
|
||||
|
||||
class ToTensorVideo:
|
||||
"""
|
||||
Convert tensor data type from uint8 to float, divide value by 255.0 and
|
||||
permute the dimensions of clip tensor
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
pass
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor, dtype=torch.uint8): Size is (T, C, H, W)
|
||||
Return:
|
||||
clip (torch.tensor, dtype=torch.float): Size is (T, C, H, W)
|
||||
"""
|
||||
return to_tensor(clip)
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return self.__class__.__name__
|
||||
|
||||
|
||||
class RandomHorizontalFlipVideo:
|
||||
"""
|
||||
Flip the video clip along the horizontal direction with a given probability
|
||||
Args:
|
||||
p (float): probability of the clip being flipped. Default value is 0.5
|
||||
"""
|
||||
|
||||
def __init__(self, p=0.5):
|
||||
self.p = p
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Size is (T, C, H, W)
|
||||
Return:
|
||||
clip (torch.tensor): Size is (T, C, H, W)
|
||||
"""
|
||||
if random.random() < self.p:
|
||||
clip = hflip(clip)
|
||||
return clip
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(p={self.p})"
|
||||
|
||||
|
||||
# ------------------------------------------------------------
|
||||
# --------------------- Sampling ---------------------------
|
||||
# ------------------------------------------------------------
|
||||
class TemporalRandomCrop(object):
|
||||
"""Temporally crop the given frame indices at a random location.
|
||||
|
||||
Args:
|
||||
size (int): Desired length of frames will be seen in the model.
|
||||
"""
|
||||
|
||||
def __init__(self, size):
|
||||
self.size = size
|
||||
|
||||
def __call__(self, total_frames):
|
||||
rand_end = max(0, total_frames - self.size - 1)
|
||||
begin_index = random.randint(0, rand_end)
|
||||
end_index = min(begin_index + self.size, total_frames)
|
||||
return begin_index, end_index
|
||||
|
||||
class DynamicSampleDuration(object):
|
||||
"""Temporally crop the given frame indices at a random location.
|
||||
|
||||
Args:
|
||||
size (int): Desired length of frames will be seen in the model.
|
||||
"""
|
||||
|
||||
def __init__(self, t_stride, extra_1):
|
||||
self.t_stride = t_stride
|
||||
self.extra_1 = extra_1
|
||||
|
||||
def __call__(self, t, h, w):
|
||||
if self.extra_1:
|
||||
t = t - 1
|
||||
truncate_t_list = list(range(t+1))[t//2:][::self.t_stride] # need half at least
|
||||
truncate_t = random.choice(truncate_t_list)
|
||||
if self.extra_1:
|
||||
truncate_t = truncate_t + 1
|
||||
return 0, truncate_t
|
||||
|
||||
if __name__ == '__main__':
|
||||
from torchvision import transforms
|
||||
import torchvision.io as io
|
||||
import numpy as np
|
||||
from torchvision.utils import save_image
|
||||
import os
|
||||
|
||||
vframes, aframes, info = io.read_video(
|
||||
filename='./v_Archery_g01_c03.avi',
|
||||
pts_unit='sec',
|
||||
output_format='TCHW'
|
||||
)
|
||||
|
||||
trans = transforms.Compose([
|
||||
ToTensorVideo(),
|
||||
RandomHorizontalFlipVideo(),
|
||||
UCFCenterCropVideo(512),
|
||||
# NormalizeVideo(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
|
||||
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True)
|
||||
])
|
||||
|
||||
target_video_len = 32
|
||||
frame_interval = 1
|
||||
total_frames = len(vframes)
|
||||
print(total_frames)
|
||||
|
||||
temporal_sample = TemporalRandomCrop(target_video_len * frame_interval)
|
||||
|
||||
# Sampling video frames
|
||||
start_frame_ind, end_frame_ind = temporal_sample(total_frames)
|
||||
# print(start_frame_ind)
|
||||
# print(end_frame_ind)
|
||||
assert end_frame_ind - start_frame_ind >= target_video_len
|
||||
frame_indice = np.linspace(start_frame_ind, end_frame_ind - 1, target_video_len, dtype=int)
|
||||
print(frame_indice)
|
||||
|
||||
select_vframes = vframes[frame_indice]
|
||||
print(select_vframes.shape)
|
||||
print(select_vframes.dtype)
|
||||
|
||||
select_vframes_trans = trans(select_vframes)
|
||||
print(select_vframes_trans.shape)
|
||||
print(select_vframes_trans.dtype)
|
||||
|
||||
select_vframes_trans_int = ((select_vframes_trans * 0.5 + 0.5) * 255).to(dtype=torch.uint8)
|
||||
print(select_vframes_trans_int.dtype)
|
||||
print(select_vframes_trans_int.permute(0, 2, 3, 1).shape)
|
||||
|
||||
io.write_video('./test.avi', select_vframes_trans_int.permute(0, 2, 3, 1), fps=8)
|
||||
|
||||
for i in range(target_video_len):
|
||||
save_image(select_vframes_trans[i], os.path.join('./test000', '%04d.png' % i), normalize=True,
|
||||
value_range=(-1, 1))
|
||||
@@ -0,0 +1,83 @@
|
||||
import numpy as np
|
||||
import torch
|
||||
from tqdm import tqdm
|
||||
import math
|
||||
from einops import rearrange
|
||||
import sys
|
||||
sys.path.append(".")
|
||||
from opensora.eval.flolpips.pwcnet import Network as PWCNet
|
||||
from opensora.eval.flolpips.flolpips import FloLPIPS
|
||||
|
||||
loss_fn = FloLPIPS(net='alex', version='0.1').eval().requires_grad_(False)
|
||||
flownet = PWCNet().eval().requires_grad_(False)
|
||||
|
||||
def trans(x):
|
||||
return x
|
||||
|
||||
|
||||
def calculate_flolpips(videos1, videos2, device):
|
||||
global loss_fn, flownet
|
||||
|
||||
print("calculate_flowlpips...")
|
||||
loss_fn = loss_fn.to(device)
|
||||
flownet = flownet.to(device)
|
||||
|
||||
if videos1.shape != videos2.shape:
|
||||
print("Warning: the shape of videos are not equal.")
|
||||
min_frames = min(videos1.shape[1], videos2.shape[1])
|
||||
videos1 = videos1[:, :min_frames]
|
||||
videos2 = videos2[:, :min_frames]
|
||||
|
||||
videos1 = trans(videos1)
|
||||
videos2 = trans(videos2)
|
||||
|
||||
flolpips_results = []
|
||||
for video_num in tqdm(range(videos1.shape[0])):
|
||||
video1 = videos1[video_num].to(device)
|
||||
video2 = videos2[video_num].to(device)
|
||||
frames_rec = video1[:-1]
|
||||
frames_rec_next = video1[1:]
|
||||
frames_gt = video2[:-1]
|
||||
frames_gt_next = video2[1:]
|
||||
t, c, h, w = frames_gt.shape
|
||||
flow_gt = flownet(frames_gt, frames_gt_next)
|
||||
flow_dis = flownet(frames_rec, frames_rec_next)
|
||||
flow_diff = flow_gt - flow_dis
|
||||
flolpips = loss_fn.forward(frames_gt, frames_rec, flow_diff, normalize=True)
|
||||
flolpips_results.append(flolpips.cpu().numpy().tolist())
|
||||
|
||||
flolpips_results = np.array(flolpips_results) # [batch_size, num_frames]
|
||||
flolpips = {}
|
||||
flolpips_std = {}
|
||||
|
||||
for clip_timestamp in range(flolpips_results.shape[1]):
|
||||
flolpips[clip_timestamp] = np.mean(flolpips_results[:,clip_timestamp], axis=-1)
|
||||
flolpips_std[clip_timestamp] = np.std(flolpips_results[:,clip_timestamp], axis=-1)
|
||||
|
||||
result = {
|
||||
"value": flolpips,
|
||||
"value_std": flolpips_std,
|
||||
"video_setting": video1.shape,
|
||||
"video_setting_name": "time, channel, heigth, width",
|
||||
"result": flolpips_results,
|
||||
"details": flolpips_results.tolist()
|
||||
}
|
||||
|
||||
return result
|
||||
|
||||
# test code / using example
|
||||
|
||||
def main():
|
||||
NUMBER_OF_VIDEOS = 8
|
||||
VIDEO_LENGTH = 50
|
||||
CHANNEL = 3
|
||||
SIZE = 64
|
||||
videos1 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
videos2 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
|
||||
import json
|
||||
result = calculate_flolpips(videos1, videos2, "cuda:0")
|
||||
print(json.dumps(result, indent=4))
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,85 @@
|
||||
import numpy as np
|
||||
import torch
|
||||
from tqdm import tqdm
|
||||
|
||||
def trans(x):
|
||||
# if greyscale images add channel
|
||||
if x.shape[-3] == 1:
|
||||
x = x.repeat(1, 1, 3, 1, 1)
|
||||
|
||||
# permute BTCHW -> BCTHW
|
||||
x = x.permute(0, 2, 1, 3, 4)
|
||||
|
||||
return x
|
||||
|
||||
def calculate_fvd(videos1, videos2, device, method='styleganv'):
|
||||
|
||||
if method == 'styleganv':
|
||||
from fvd.styleganv.fvd import get_fvd_feats, frechet_distance, load_i3d_pretrained
|
||||
elif method == 'videogpt':
|
||||
from fvd.videogpt.fvd import load_i3d_pretrained
|
||||
from fvd.videogpt.fvd import get_fvd_logits as get_fvd_feats
|
||||
from fvd.videogpt.fvd import frechet_distance
|
||||
|
||||
print("calculate_fvd...")
|
||||
|
||||
# videos [batch_size, timestamps, channel, h, w]
|
||||
|
||||
assert videos1.shape == videos2.shape
|
||||
|
||||
i3d = load_i3d_pretrained(device=device)
|
||||
fvd_results = []
|
||||
|
||||
# support grayscale input, if grayscale -> channel*3
|
||||
# BTCHW -> BCTHW
|
||||
# videos -> [batch_size, channel, timestamps, h, w]
|
||||
|
||||
videos1 = trans(videos1)
|
||||
videos2 = trans(videos2)
|
||||
|
||||
fvd_results = {}
|
||||
|
||||
# for calculate FVD, each clip_timestamp must >= 10
|
||||
for clip_timestamp in tqdm(range(10, videos1.shape[-3]+1)):
|
||||
|
||||
# get a video clip
|
||||
# videos_clip [batch_size, channel, timestamps[:clip], h, w]
|
||||
videos_clip1 = videos1[:, :, : clip_timestamp]
|
||||
videos_clip2 = videos2[:, :, : clip_timestamp]
|
||||
|
||||
# get FVD features
|
||||
feats1 = get_fvd_feats(videos_clip1, i3d=i3d, device=device)
|
||||
feats2 = get_fvd_feats(videos_clip2, i3d=i3d, device=device)
|
||||
|
||||
# calculate FVD when timestamps[:clip]
|
||||
fvd_results[clip_timestamp] = frechet_distance(feats1, feats2)
|
||||
|
||||
result = {
|
||||
"value": fvd_results,
|
||||
"video_setting": videos1.shape,
|
||||
"video_setting_name": "batch_size, channel, time, heigth, width",
|
||||
}
|
||||
|
||||
return result
|
||||
|
||||
# test code / using example
|
||||
|
||||
def main():
|
||||
NUMBER_OF_VIDEOS = 8
|
||||
VIDEO_LENGTH = 50
|
||||
CHANNEL = 3
|
||||
SIZE = 64
|
||||
videos1 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
videos2 = torch.ones(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
device = torch.device("cuda")
|
||||
# device = torch.device("cpu")
|
||||
|
||||
import json
|
||||
result = calculate_fvd(videos1, videos2, device, method='videogpt')
|
||||
print(json.dumps(result, indent=4))
|
||||
|
||||
result = calculate_fvd(videos1, videos2, device, method='styleganv')
|
||||
print(json.dumps(result, indent=4))
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,97 @@
|
||||
import numpy as np
|
||||
import torch
|
||||
from tqdm import tqdm
|
||||
import math
|
||||
|
||||
import torch
|
||||
import lpips
|
||||
|
||||
spatial = True # Return a spatial map of perceptual distance.
|
||||
|
||||
# Linearly calibrated models (LPIPS)
|
||||
loss_fn = lpips.LPIPS(net='alex', spatial=spatial) # Can also set net = 'squeeze' or 'vgg'
|
||||
# loss_fn = lpips.LPIPS(net='alex', spatial=spatial, lpips=False) # Can also set net = 'squeeze' or 'vgg'
|
||||
|
||||
def trans(x):
|
||||
# if greyscale images add channel
|
||||
if x.shape[-3] == 1:
|
||||
x = x.repeat(1, 1, 3, 1, 1)
|
||||
|
||||
# value range [0, 1] -> [-1, 1]
|
||||
x = x * 2 - 1
|
||||
|
||||
return x
|
||||
|
||||
def calculate_lpips(videos1, videos2, device):
|
||||
# image should be RGB, IMPORTANT: normalized to [-1,1]
|
||||
print("calculate_lpips...")
|
||||
|
||||
assert videos1.shape == videos2.shape
|
||||
|
||||
# videos [batch_size, timestamps, channel, h, w]
|
||||
|
||||
# support grayscale input, if grayscale -> channel*3
|
||||
# value range [0, 1] -> [-1, 1]
|
||||
videos1 = trans(videos1)
|
||||
videos2 = trans(videos2)
|
||||
|
||||
lpips_results = []
|
||||
|
||||
for video_num in tqdm(range(videos1.shape[0])):
|
||||
# get a video
|
||||
# video [timestamps, channel, h, w]
|
||||
video1 = videos1[video_num]
|
||||
video2 = videos2[video_num]
|
||||
|
||||
lpips_results_of_a_video = []
|
||||
for clip_timestamp in range(len(video1)):
|
||||
# get a img
|
||||
# img [timestamps[x], channel, h, w]
|
||||
# img [channel, h, w] tensor
|
||||
|
||||
img1 = video1[clip_timestamp].unsqueeze(0).to(device)
|
||||
img2 = video2[clip_timestamp].unsqueeze(0).to(device)
|
||||
|
||||
loss_fn.to(device)
|
||||
|
||||
# calculate lpips of a video
|
||||
lpips_results_of_a_video.append(loss_fn.forward(img1, img2).mean().detach().cpu().tolist())
|
||||
lpips_results.append(lpips_results_of_a_video)
|
||||
|
||||
lpips_results = np.array(lpips_results)
|
||||
|
||||
lpips = {}
|
||||
lpips_std = {}
|
||||
|
||||
for clip_timestamp in range(len(video1)):
|
||||
lpips[clip_timestamp] = np.mean(lpips_results[:,clip_timestamp])
|
||||
lpips_std[clip_timestamp] = np.std(lpips_results[:,clip_timestamp])
|
||||
|
||||
|
||||
result = {
|
||||
"value": lpips,
|
||||
"value_std": lpips_std,
|
||||
"video_setting": video1.shape,
|
||||
"video_setting_name": "time, channel, heigth, width",
|
||||
}
|
||||
|
||||
return result
|
||||
|
||||
# test code / using example
|
||||
|
||||
def main():
|
||||
NUMBER_OF_VIDEOS = 8
|
||||
VIDEO_LENGTH = 50
|
||||
CHANNEL = 3
|
||||
SIZE = 64
|
||||
videos1 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
videos2 = torch.ones(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
device = torch.device("cuda")
|
||||
# device = torch.device("cpu")
|
||||
|
||||
import json
|
||||
result = calculate_lpips(videos1, videos2, device)
|
||||
print(json.dumps(result, indent=4))
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,84 @@
|
||||
import numpy as np
|
||||
import torch
|
||||
from tqdm import tqdm
|
||||
import math
|
||||
|
||||
def img_psnr(img1, img2):
|
||||
# [0,1]
|
||||
# compute mse
|
||||
# mse = np.mean((img1-img2)**2)
|
||||
mse = np.mean((img1 / 1.0 - img2 / 1.0) ** 2)
|
||||
# compute psnr
|
||||
if mse < 1e-10:
|
||||
return 100
|
||||
psnr = 20 * math.log10(1 / math.sqrt(mse))
|
||||
return psnr
|
||||
|
||||
def trans(x):
|
||||
return x
|
||||
|
||||
def calculate_psnr(videos1, videos2):
|
||||
print("calculate_psnr...")
|
||||
|
||||
# videos [batch_size, timestamps, channel, h, w]
|
||||
|
||||
assert videos1.shape == videos2.shape
|
||||
|
||||
videos1 = trans(videos1)
|
||||
videos2 = trans(videos2)
|
||||
|
||||
psnr_results = []
|
||||
|
||||
for video_num in tqdm(range(videos1.shape[0])):
|
||||
# get a video
|
||||
# video [timestamps, channel, h, w]
|
||||
video1 = videos1[video_num]
|
||||
video2 = videos2[video_num]
|
||||
|
||||
psnr_results_of_a_video = []
|
||||
for clip_timestamp in range(len(video1)):
|
||||
# get a img
|
||||
# img [timestamps[x], channel, h, w]
|
||||
# img [channel, h, w] numpy
|
||||
|
||||
img1 = video1[clip_timestamp].numpy()
|
||||
img2 = video2[clip_timestamp].numpy()
|
||||
|
||||
# calculate psnr of a video
|
||||
psnr_results_of_a_video.append(img_psnr(img1, img2))
|
||||
|
||||
psnr_results.append(psnr_results_of_a_video)
|
||||
|
||||
psnr_results = np.array(psnr_results) # [batch_size, num_frames]
|
||||
psnr = {}
|
||||
psnr_std = {}
|
||||
|
||||
for clip_timestamp in range(len(video1)):
|
||||
psnr[clip_timestamp] = np.mean(psnr_results[:,clip_timestamp])
|
||||
psnr_std[clip_timestamp] = np.std(psnr_results[:,clip_timestamp])
|
||||
|
||||
result = {
|
||||
"value": psnr,
|
||||
"value_std": psnr_std,
|
||||
"video_setting": video1.shape,
|
||||
"video_setting_name": "time, channel, heigth, width",
|
||||
}
|
||||
|
||||
return result
|
||||
|
||||
# test code / using example
|
||||
|
||||
def main():
|
||||
NUMBER_OF_VIDEOS = 8
|
||||
VIDEO_LENGTH = 50
|
||||
CHANNEL = 3
|
||||
SIZE = 64
|
||||
videos1 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
videos2 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
|
||||
import json
|
||||
result = calculate_psnr(videos1, videos2)
|
||||
print(json.dumps(result, indent=4))
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,113 @@
|
||||
import numpy as np
|
||||
import torch
|
||||
from tqdm import tqdm
|
||||
import cv2
|
||||
|
||||
def ssim(img1, img2):
|
||||
C1 = 0.01 ** 2
|
||||
C2 = 0.03 ** 2
|
||||
img1 = img1.astype(np.float64)
|
||||
img2 = img2.astype(np.float64)
|
||||
kernel = cv2.getGaussianKernel(11, 1.5)
|
||||
window = np.outer(kernel, kernel.transpose())
|
||||
mu1 = cv2.filter2D(img1, -1, window)[5:-5, 5:-5] # valid
|
||||
mu2 = cv2.filter2D(img2, -1, window)[5:-5, 5:-5]
|
||||
mu1_sq = mu1 ** 2
|
||||
mu2_sq = mu2 ** 2
|
||||
mu1_mu2 = mu1 * mu2
|
||||
sigma1_sq = cv2.filter2D(img1 ** 2, -1, window)[5:-5, 5:-5] - mu1_sq
|
||||
sigma2_sq = cv2.filter2D(img2 ** 2, -1, window)[5:-5, 5:-5] - mu2_sq
|
||||
sigma12 = cv2.filter2D(img1 * img2, -1, window)[5:-5, 5:-5] - mu1_mu2
|
||||
ssim_map = ((2 * mu1_mu2 + C1) * (2 * sigma12 + C2)) / ((mu1_sq + mu2_sq + C1) *
|
||||
(sigma1_sq + sigma2_sq + C2))
|
||||
return ssim_map.mean()
|
||||
|
||||
|
||||
def calculate_ssim_function(img1, img2):
|
||||
# [0,1]
|
||||
# ssim is the only metric extremely sensitive to gray being compared to b/w
|
||||
if not img1.shape == img2.shape:
|
||||
raise ValueError('Input images must have the same dimensions.')
|
||||
if img1.ndim == 2:
|
||||
return ssim(img1, img2)
|
||||
elif img1.ndim == 3:
|
||||
if img1.shape[0] == 3:
|
||||
ssims = []
|
||||
for i in range(3):
|
||||
ssims.append(ssim(img1[i], img2[i]))
|
||||
return np.array(ssims).mean()
|
||||
elif img1.shape[0] == 1:
|
||||
return ssim(np.squeeze(img1), np.squeeze(img2))
|
||||
else:
|
||||
raise ValueError('Wrong input image dimensions.')
|
||||
|
||||
def trans(x):
|
||||
return x
|
||||
|
||||
def calculate_ssim(videos1, videos2):
|
||||
print("calculate_ssim...")
|
||||
|
||||
# videos [batch_size, timestamps, channel, h, w]
|
||||
|
||||
assert videos1.shape == videos2.shape
|
||||
|
||||
videos1 = trans(videos1)
|
||||
videos2 = trans(videos2)
|
||||
|
||||
ssim_results = []
|
||||
|
||||
for video_num in tqdm(range(videos1.shape[0])):
|
||||
# get a video
|
||||
# video [timestamps, channel, h, w]
|
||||
video1 = videos1[video_num]
|
||||
video2 = videos2[video_num]
|
||||
|
||||
ssim_results_of_a_video = []
|
||||
for clip_timestamp in range(len(video1)):
|
||||
# get a img
|
||||
# img [timestamps[x], channel, h, w]
|
||||
# img [channel, h, w] numpy
|
||||
|
||||
img1 = video1[clip_timestamp].numpy()
|
||||
img2 = video2[clip_timestamp].numpy()
|
||||
|
||||
# calculate ssim of a video
|
||||
ssim_results_of_a_video.append(calculate_ssim_function(img1, img2))
|
||||
|
||||
ssim_results.append(ssim_results_of_a_video)
|
||||
|
||||
ssim_results = np.array(ssim_results)
|
||||
|
||||
ssim = {}
|
||||
ssim_std = {}
|
||||
|
||||
for clip_timestamp in range(len(video1)):
|
||||
ssim[clip_timestamp] = np.mean(ssim_results[:,clip_timestamp])
|
||||
ssim_std[clip_timestamp] = np.std(ssim_results[:,clip_timestamp])
|
||||
|
||||
result = {
|
||||
"value": ssim,
|
||||
"value_std": ssim_std,
|
||||
"video_setting": video1.shape,
|
||||
"video_setting_name": "time, channel, heigth, width",
|
||||
}
|
||||
|
||||
return result
|
||||
|
||||
# test code / using example
|
||||
|
||||
def main():
|
||||
NUMBER_OF_VIDEOS = 8
|
||||
VIDEO_LENGTH = 50
|
||||
CHANNEL = 3
|
||||
SIZE = 64
|
||||
videos1 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
videos2 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
device = torch.device("cuda")
|
||||
|
||||
import json
|
||||
result = calculate_ssim(videos1, videos2)
|
||||
print(json.dumps(result, indent=4))
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
Executable
+225
@@ -0,0 +1,225 @@
|
||||
"""Calculates the CLIP Scores
|
||||
|
||||
The CLIP model is a contrasitively learned language-image model. There is
|
||||
an image encoder and a text encoder. It is believed that the CLIP model could
|
||||
measure the similarity of cross modalities. Please find more information from
|
||||
https://github.com/openai/CLIP.
|
||||
|
||||
The CLIP Score measures the Cosine Similarity between two embedded features.
|
||||
This repository utilizes the pretrained CLIP Model to calculate
|
||||
the mean average of cosine similarities.
|
||||
|
||||
See --help to see further details.
|
||||
|
||||
Code apapted from https://github.com/mseitzer/pytorch-fid and https://github.com/openai/CLIP.
|
||||
|
||||
Copyright 2023 The Hong Kong Polytechnic University
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
"""
|
||||
import os
|
||||
import os.path as osp
|
||||
from argparse import ArgumentDefaultsHelpFormatter, ArgumentParser
|
||||
|
||||
import clip
|
||||
import torch
|
||||
from PIL import Image
|
||||
from torch.utils.data import Dataset, DataLoader
|
||||
|
||||
try:
|
||||
from tqdm import tqdm
|
||||
except ImportError:
|
||||
# If tqdm is not available, provide a mock version of it
|
||||
def tqdm(x):
|
||||
return x
|
||||
|
||||
|
||||
IMAGE_EXTENSIONS = {'bmp', 'jpg', 'jpeg', 'pgm', 'png', 'ppm',
|
||||
'tif', 'tiff', 'webp'}
|
||||
|
||||
TEXT_EXTENSIONS = {'txt'}
|
||||
|
||||
|
||||
class DummyDataset(Dataset):
|
||||
|
||||
FLAGS = ['img', 'txt']
|
||||
def __init__(self, real_path, generated_path,
|
||||
real_flag: str = 'img',
|
||||
generated_flag: str = 'img',
|
||||
transform = None,
|
||||
tokenizer = None) -> None:
|
||||
super().__init__()
|
||||
assert real_flag in self.FLAGS and generated_flag in self.FLAGS, \
|
||||
'CLIP Score only support modality of {}. However, get {} and {}'.format(
|
||||
self.FLAGS, real_flag, generated_flag
|
||||
)
|
||||
self.real_folder = self._combine_without_prefix(real_path)
|
||||
self.real_flag = real_flag
|
||||
self.fake_foler = self._combine_without_prefix(generated_path)
|
||||
self.generated_flag = generated_flag
|
||||
self.transform = transform
|
||||
self.tokenizer = tokenizer
|
||||
# assert self._check()
|
||||
|
||||
def __len__(self):
|
||||
return len(self.real_folder)
|
||||
|
||||
def __getitem__(self, index):
|
||||
if index >= len(self):
|
||||
raise IndexError
|
||||
real_path = self.real_folder[index]
|
||||
generated_path = self.fake_foler[index]
|
||||
real_data = self._load_modality(real_path, self.real_flag)
|
||||
fake_data = self._load_modality(generated_path, self.generated_flag)
|
||||
|
||||
sample = dict(real=real_data, fake=fake_data)
|
||||
return sample
|
||||
|
||||
def _load_modality(self, path, modality):
|
||||
if modality == 'img':
|
||||
data = self._load_img(path)
|
||||
elif modality == 'txt':
|
||||
data = self._load_txt(path)
|
||||
else:
|
||||
raise TypeError("Got unexpected modality: {}".format(modality))
|
||||
return data
|
||||
|
||||
def _load_img(self, path):
|
||||
img = Image.open(path)
|
||||
if self.transform is not None:
|
||||
img = self.transform(img)
|
||||
return img
|
||||
|
||||
def _load_txt(self, path):
|
||||
with open(path, 'r') as fp:
|
||||
data = fp.read()
|
||||
fp.close()
|
||||
if self.tokenizer is not None:
|
||||
data = self.tokenizer(data).squeeze()
|
||||
return data
|
||||
|
||||
def _check(self):
|
||||
for idx in range(len(self)):
|
||||
real_name = self.real_folder[idx].split('.')
|
||||
fake_name = self.fake_folder[idx].split('.')
|
||||
if fake_name != real_name:
|
||||
return False
|
||||
return True
|
||||
|
||||
def _combine_without_prefix(self, folder_path, prefix='.'):
|
||||
folder = []
|
||||
for name in os.listdir(folder_path):
|
||||
if name[0] == prefix:
|
||||
continue
|
||||
folder.append(osp.join(folder_path, name))
|
||||
folder.sort()
|
||||
return folder
|
||||
|
||||
|
||||
@torch.no_grad()
|
||||
def calculate_clip_score(dataloader, model, real_flag, generated_flag):
|
||||
score_acc = 0.
|
||||
sample_num = 0.
|
||||
logit_scale = model.logit_scale.exp()
|
||||
for batch_data in tqdm(dataloader):
|
||||
real = batch_data['real']
|
||||
real_features = forward_modality(model, real, real_flag)
|
||||
fake = batch_data['fake']
|
||||
fake_features = forward_modality(model, fake, generated_flag)
|
||||
|
||||
# normalize features
|
||||
real_features = real_features / real_features.norm(dim=1, keepdim=True).to(torch.float32)
|
||||
fake_features = fake_features / fake_features.norm(dim=1, keepdim=True).to(torch.float32)
|
||||
|
||||
# calculate scores
|
||||
# score = logit_scale * real_features @ fake_features.t()
|
||||
# score_acc += torch.diag(score).sum()
|
||||
score = logit_scale * (fake_features * real_features).sum()
|
||||
score_acc += score
|
||||
sample_num += real.shape[0]
|
||||
|
||||
return score_acc / sample_num
|
||||
|
||||
|
||||
def forward_modality(model, data, flag):
|
||||
device = next(model.parameters()).device
|
||||
if flag == 'img':
|
||||
features = model.encode_image(data.to(device))
|
||||
elif flag == 'txt':
|
||||
features = model.encode_text(data.to(device))
|
||||
else:
|
||||
raise TypeError
|
||||
return features
|
||||
|
||||
|
||||
def main():
|
||||
parser = ArgumentParser(formatter_class=ArgumentDefaultsHelpFormatter)
|
||||
parser.add_argument('--batch-size', type=int, default=50,
|
||||
help='Batch size to use')
|
||||
parser.add_argument('--clip-model', type=str, default='ViT-B/32',
|
||||
help='CLIP model to use')
|
||||
parser.add_argument('--num-workers', type=int, default=8,
|
||||
help=('Number of processes to use for data loading. '
|
||||
'Defaults to `min(8, num_cpus)`'))
|
||||
parser.add_argument('--device', type=str, default=None,
|
||||
help='Device to use. Like cuda, cuda:0 or cpu')
|
||||
parser.add_argument('--real_flag', type=str, default='img',
|
||||
help=('The modality of real path. '
|
||||
'Default to img'))
|
||||
parser.add_argument('--generated_flag', type=str, default='txt',
|
||||
help=('The modality of generated path. '
|
||||
'Default to txt'))
|
||||
parser.add_argument('--real_path', type=str,
|
||||
help=('Paths to the real images or '
|
||||
'to .npz statistic files'))
|
||||
parser.add_argument('--generated_path', type=str,
|
||||
help=('Paths to the generated images or '
|
||||
'to .npz statistic files'))
|
||||
args = parser.parse_args()
|
||||
|
||||
if args.device is None:
|
||||
device = torch.device('cuda' if (torch.cuda.is_available()) else 'cpu')
|
||||
else:
|
||||
device = torch.device(args.device)
|
||||
|
||||
if args.num_workers is None:
|
||||
try:
|
||||
num_cpus = len(os.sched_getaffinity(0))
|
||||
except AttributeError:
|
||||
# os.sched_getaffinity is not available under Windows, use
|
||||
# os.cpu_count instead (which may not return the *available* number
|
||||
# of CPUs).
|
||||
num_cpus = os.cpu_count()
|
||||
|
||||
num_workers = min(num_cpus, 8) if num_cpus is not None else 0
|
||||
else:
|
||||
num_workers = args.num_workers
|
||||
|
||||
print('Loading CLIP model: {}'.format(args.clip_model))
|
||||
model, preprocess = clip.load(args.clip_model, device=device)
|
||||
|
||||
dataset = DummyDataset(args.real_path, args.generated_path,
|
||||
args.real_flag, args.generated_flag,
|
||||
transform=preprocess, tokenizer=clip.tokenize)
|
||||
dataloader = DataLoader(dataset, args.batch_size,
|
||||
num_workers=num_workers, pin_memory=True)
|
||||
|
||||
print('Calculating CLIP Score:')
|
||||
clip_score = calculate_clip_score(dataloader, model,
|
||||
args.real_flag, args.generated_flag)
|
||||
clip_score = clip_score.cpu().item()
|
||||
print('CLIP Score: ', clip_score)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
main()
|
||||
@@ -0,0 +1,224 @@
|
||||
"""Calculates the CLIP Scores
|
||||
|
||||
The CLIP model is a contrasitively learned language-image model. There is
|
||||
an image encoder and a text encoder. It is believed that the CLIP model could
|
||||
measure the similarity of cross modalities. Please find more information from
|
||||
https://github.com/openai/CLIP.
|
||||
|
||||
The CLIP Score measures the Cosine Similarity between two embedded features.
|
||||
This repository utilizes the pretrained CLIP Model to calculate
|
||||
the mean average of cosine similarities.
|
||||
|
||||
See --help to see further details.
|
||||
|
||||
Code apapted from https://github.com/mseitzer/pytorch-fid and https://github.com/openai/CLIP.
|
||||
|
||||
Copyright 2023 The Hong Kong Polytechnic University
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
"""
|
||||
|
||||
import os
|
||||
import os.path as osp
|
||||
from argparse import ArgumentDefaultsHelpFormatter, ArgumentParser
|
||||
import numpy as np
|
||||
import torch
|
||||
from torch.utils.data import Dataset, DataLoader, Subset
|
||||
from decord import VideoReader, cpu
|
||||
import random
|
||||
from pytorchvideo.transforms import ShortSideScale
|
||||
from torchvision.io import read_video
|
||||
from torchvision.transforms import Lambda, Compose
|
||||
from torchvision.transforms._transforms_video import CenterCropVideo
|
||||
import sys
|
||||
sys.path.append(".")
|
||||
from opensora.eval.cal_lpips import calculate_lpips
|
||||
from opensora.eval.cal_fvd import calculate_fvd
|
||||
from opensora.eval.cal_psnr import calculate_psnr
|
||||
from opensora.eval.cal_flolpips import calculate_flolpips
|
||||
from opensora.eval.cal_ssim import calculate_ssim
|
||||
|
||||
try:
|
||||
from tqdm import tqdm
|
||||
except ImportError:
|
||||
# If tqdm is not available, provide a mock version of it
|
||||
def tqdm(x):
|
||||
return x
|
||||
|
||||
class VideoDataset(Dataset):
|
||||
def __init__(self,
|
||||
real_video_dir,
|
||||
generated_video_dir,
|
||||
num_frames,
|
||||
sample_rate = 1,
|
||||
crop_size=None,
|
||||
resolution=128,
|
||||
) -> None:
|
||||
super().__init__()
|
||||
self.real_video_files = self._combine_without_prefix(real_video_dir)
|
||||
self.generated_video_files = self._combine_without_prefix(generated_video_dir)
|
||||
self.num_frames = num_frames
|
||||
self.sample_rate = sample_rate
|
||||
self.crop_size = crop_size
|
||||
self.short_size = resolution
|
||||
|
||||
|
||||
def __len__(self):
|
||||
return len(self.real_video_files)
|
||||
|
||||
def __getitem__(self, index):
|
||||
if index >= len(self):
|
||||
raise IndexError
|
||||
real_video_file = self.real_video_files[index]
|
||||
generated_video_file = self.generated_video_files[index]
|
||||
print(real_video_file, generated_video_file)
|
||||
real_video_tensor = self._load_video(real_video_file)
|
||||
generated_video_tensor = self._load_video(generated_video_file)
|
||||
return {'real': real_video_tensor, 'generated':generated_video_tensor }
|
||||
|
||||
|
||||
def _load_video(self, video_path):
|
||||
num_frames = self.num_frames
|
||||
sample_rate = self.sample_rate
|
||||
decord_vr = VideoReader(video_path, ctx=cpu(0))
|
||||
total_frames = len(decord_vr)
|
||||
sample_frames_len = sample_rate * num_frames
|
||||
|
||||
if total_frames >= sample_frames_len:
|
||||
s = 0
|
||||
e = s + sample_frames_len
|
||||
num_frames = num_frames
|
||||
else:
|
||||
s = 0
|
||||
e = total_frames
|
||||
num_frames = int(total_frames / sample_frames_len * num_frames)
|
||||
print(f'sample_frames_len {sample_frames_len}, only can sample {num_frames * sample_rate}', video_path,
|
||||
total_frames)
|
||||
|
||||
|
||||
frame_id_list = np.linspace(s, e - 1, num_frames, dtype=int)
|
||||
video_data = decord_vr.get_batch(frame_id_list).asnumpy()
|
||||
video_data = torch.from_numpy(video_data)
|
||||
video_data = video_data.permute(0, 3, 1, 2) # (T, H, W, C) -> (C, T, H, W)
|
||||
return _preprocess(video_data, short_size=self.short_size, crop_size = self.crop_size)
|
||||
|
||||
|
||||
def _combine_without_prefix(self, folder_path, prefix='.'):
|
||||
folder = []
|
||||
os.makedirs(folder_path, exist_ok=True)
|
||||
for name in os.listdir(folder_path):
|
||||
if name[0] == prefix:
|
||||
continue
|
||||
if osp.isfile(osp.join(folder_path, name)):
|
||||
folder.append(osp.join(folder_path, name))
|
||||
folder.sort()
|
||||
return folder
|
||||
|
||||
def _preprocess(video_data, short_size=128, crop_size=None):
|
||||
transform = Compose(
|
||||
[
|
||||
Lambda(lambda x: x / 255.0),
|
||||
ShortSideScale(size=short_size),
|
||||
CenterCropVideo(crop_size=crop_size),
|
||||
]
|
||||
)
|
||||
video_outputs = transform(video_data)
|
||||
# video_outputs = torch.unsqueeze(video_outputs, 0) # (bz,c,t,h,w)
|
||||
return video_outputs
|
||||
|
||||
|
||||
def calculate_common_metric(args, dataloader, device):
|
||||
|
||||
score_list = []
|
||||
for batch_data in tqdm(dataloader): # {'real': real_video_tensor, 'generated':generated_video_tensor }
|
||||
real_videos = batch_data['real']
|
||||
generated_videos = batch_data['generated']
|
||||
assert real_videos.shape[2] == generated_videos.shape[2]
|
||||
if args.metric == 'fvd':
|
||||
tmp_list = list(calculate_fvd(real_videos, generated_videos, args.device, method=args.fvd_method)['value'].values())
|
||||
elif args.metric == 'ssim':
|
||||
tmp_list = list(calculate_ssim(real_videos, generated_videos)['value'].values())
|
||||
elif args.metric == 'psnr':
|
||||
tmp_list = list(calculate_psnr(real_videos, generated_videos)['value'].values())
|
||||
elif args.metric == 'flolpips':
|
||||
result = calculate_flolpips(real_videos, generated_videos, args.device)
|
||||
tmp_list = list(result['value'].values())
|
||||
else:
|
||||
tmp_list = list(calculate_lpips(real_videos, generated_videos, args.device)['value'].values())
|
||||
score_list += tmp_list
|
||||
return np.mean(score_list)
|
||||
|
||||
def main():
|
||||
parser = ArgumentParser(formatter_class=ArgumentDefaultsHelpFormatter)
|
||||
parser.add_argument('--batch_size', type=int, default=2,
|
||||
help='Batch size to use')
|
||||
parser.add_argument('--real_video_dir', type=str,
|
||||
help=('the path of real videos`'))
|
||||
parser.add_argument('--generated_video_dir', type=str,
|
||||
help=('the path of generated videos`'))
|
||||
parser.add_argument('--device', type=str, default=None,
|
||||
help='Device to use. Like cuda, cuda:0 or cpu')
|
||||
parser.add_argument('--num_workers', type=int, default=8,
|
||||
help=('Number of processes to use for data loading. '
|
||||
'Defaults to `min(8, num_cpus)`'))
|
||||
parser.add_argument('--sample_fps', type=int, default=30)
|
||||
parser.add_argument('--resolution', type=int, default=336)
|
||||
parser.add_argument('--crop_size', type=int, default=None)
|
||||
parser.add_argument('--num_frames', type=int, default=100)
|
||||
parser.add_argument('--sample_rate', type=int, default=1)
|
||||
parser.add_argument('--subset_size', type=int, default=None)
|
||||
parser.add_argument("--metric", type=str, default="fvd",choices=['fvd','psnr','ssim','lpips', 'flolpips'])
|
||||
parser.add_argument("--fvd_method", type=str, default='styleganv',choices=['styleganv','videogpt'])
|
||||
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
if args.device is None:
|
||||
device = torch.device('cuda' if (torch.cuda.is_available()) else 'cpu')
|
||||
else:
|
||||
device = torch.device(args.device)
|
||||
|
||||
if args.num_workers is None:
|
||||
try:
|
||||
num_cpus = len(os.sched_getaffinity(0))
|
||||
except AttributeError:
|
||||
# os.sched_getaffinity is not available under Windows, use
|
||||
# os.cpu_count instead (which may not return the *available* number
|
||||
# of CPUs).
|
||||
num_cpus = os.cpu_count()
|
||||
|
||||
num_workers = min(num_cpus, 8) if num_cpus is not None else 0
|
||||
else:
|
||||
num_workers = args.num_workers
|
||||
|
||||
|
||||
dataset = VideoDataset(args.real_video_dir,
|
||||
args.generated_video_dir,
|
||||
num_frames = args.num_frames,
|
||||
sample_rate = args.sample_rate,
|
||||
crop_size=args.crop_size,
|
||||
resolution=args.resolution)
|
||||
|
||||
if args.subset_size:
|
||||
indices = range(args.subset_size)
|
||||
dataset = Subset(dataset, indices=indices)
|
||||
|
||||
dataloader = DataLoader(dataset, args.batch_size,
|
||||
num_workers=num_workers, pin_memory=True)
|
||||
|
||||
|
||||
metric_score = calculate_common_metric(args, dataloader,device)
|
||||
print('metric: ', args.metric, " ",metric_score)
|
||||
|
||||
if __name__ == '__main__':
|
||||
main()
|
||||
@@ -0,0 +1,397 @@
|
||||
#!/usr/bin/env python
|
||||
|
||||
import torch
|
||||
|
||||
import cupy
|
||||
import re
|
||||
|
||||
kernel_Correlation_rearrange = '''
|
||||
extern "C" __global__ void kernel_Correlation_rearrange(
|
||||
const int n,
|
||||
const float* input,
|
||||
float* output
|
||||
) {
|
||||
int intIndex = (blockIdx.x * blockDim.x) + threadIdx.x;
|
||||
|
||||
if (intIndex >= n) {
|
||||
return;
|
||||
}
|
||||
|
||||
int intSample = blockIdx.z;
|
||||
int intChannel = blockIdx.y;
|
||||
|
||||
float fltValue = input[(((intSample * SIZE_1(input)) + intChannel) * SIZE_2(input) * SIZE_3(input)) + intIndex];
|
||||
|
||||
__syncthreads();
|
||||
|
||||
int intPaddedY = (intIndex / SIZE_3(input)) + 4;
|
||||
int intPaddedX = (intIndex % SIZE_3(input)) + 4;
|
||||
int intRearrange = ((SIZE_3(input) + 8) * intPaddedY) + intPaddedX;
|
||||
|
||||
output[(((intSample * SIZE_1(output) * SIZE_2(output)) + intRearrange) * SIZE_1(input)) + intChannel] = fltValue;
|
||||
}
|
||||
'''
|
||||
|
||||
kernel_Correlation_updateOutput = '''
|
||||
extern "C" __global__ void kernel_Correlation_updateOutput(
|
||||
const int n,
|
||||
const float* rbot0,
|
||||
const float* rbot1,
|
||||
float* top
|
||||
) {
|
||||
extern __shared__ char patch_data_char[];
|
||||
|
||||
float *patch_data = (float *)patch_data_char;
|
||||
|
||||
// First (upper left) position of kernel upper-left corner in current center position of neighborhood in image 1
|
||||
int x1 = blockIdx.x + 4;
|
||||
int y1 = blockIdx.y + 4;
|
||||
int item = blockIdx.z;
|
||||
int ch_off = threadIdx.x;
|
||||
|
||||
// Load 3D patch into shared shared memory
|
||||
for (int j = 0; j < 1; j++) { // HEIGHT
|
||||
for (int i = 0; i < 1; i++) { // WIDTH
|
||||
int ji_off = (j + i) * SIZE_3(rbot0);
|
||||
for (int ch = ch_off; ch < SIZE_3(rbot0); ch += 32) { // CHANNELS
|
||||
int idx1 = ((item * SIZE_1(rbot0) + y1+j) * SIZE_2(rbot0) + x1+i) * SIZE_3(rbot0) + ch;
|
||||
int idxPatchData = ji_off + ch;
|
||||
patch_data[idxPatchData] = rbot0[idx1];
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
__syncthreads();
|
||||
|
||||
__shared__ float sum[32];
|
||||
|
||||
// Compute correlation
|
||||
for (int top_channel = 0; top_channel < SIZE_1(top); top_channel++) {
|
||||
sum[ch_off] = 0;
|
||||
|
||||
int s2o = top_channel % 9 - 4;
|
||||
int s2p = top_channel / 9 - 4;
|
||||
|
||||
for (int j = 0; j < 1; j++) { // HEIGHT
|
||||
for (int i = 0; i < 1; i++) { // WIDTH
|
||||
int ji_off = (j + i) * SIZE_3(rbot0);
|
||||
for (int ch = ch_off; ch < SIZE_3(rbot0); ch += 32) { // CHANNELS
|
||||
int x2 = x1 + s2o;
|
||||
int y2 = y1 + s2p;
|
||||
|
||||
int idxPatchData = ji_off + ch;
|
||||
int idx2 = ((item * SIZE_1(rbot0) + y2+j) * SIZE_2(rbot0) + x2+i) * SIZE_3(rbot0) + ch;
|
||||
|
||||
sum[ch_off] += patch_data[idxPatchData] * rbot1[idx2];
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
__syncthreads();
|
||||
|
||||
if (ch_off == 0) {
|
||||
float total_sum = 0;
|
||||
for (int idx = 0; idx < 32; idx++) {
|
||||
total_sum += sum[idx];
|
||||
}
|
||||
const int sumelems = SIZE_3(rbot0);
|
||||
const int index = ((top_channel*SIZE_2(top) + blockIdx.y)*SIZE_3(top))+blockIdx.x;
|
||||
top[index + item*SIZE_1(top)*SIZE_2(top)*SIZE_3(top)] = total_sum / (float)sumelems;
|
||||
}
|
||||
}
|
||||
}
|
||||
'''
|
||||
|
||||
kernel_Correlation_updateGradFirst = '''
|
||||
#define ROUND_OFF 50000
|
||||
|
||||
extern "C" __global__ void kernel_Correlation_updateGradFirst(
|
||||
const int n,
|
||||
const int intSample,
|
||||
const float* rbot0,
|
||||
const float* rbot1,
|
||||
const float* gradOutput,
|
||||
float* gradFirst,
|
||||
float* gradSecond
|
||||
) { for (int intIndex = (blockIdx.x * blockDim.x) + threadIdx.x; intIndex < n; intIndex += blockDim.x * gridDim.x) {
|
||||
int n = intIndex % SIZE_1(gradFirst); // channels
|
||||
int l = (intIndex / SIZE_1(gradFirst)) % SIZE_3(gradFirst) + 4; // w-pos
|
||||
int m = (intIndex / SIZE_1(gradFirst) / SIZE_3(gradFirst)) % SIZE_2(gradFirst) + 4; // h-pos
|
||||
|
||||
// round_off is a trick to enable integer division with ceil, even for negative numbers
|
||||
// We use a large offset, for the inner part not to become negative.
|
||||
const int round_off = ROUND_OFF;
|
||||
const int round_off_s1 = round_off;
|
||||
|
||||
// We add round_off before_s1 the int division and subtract round_off after it, to ensure the formula matches ceil behavior:
|
||||
int xmin = (l - 4 + round_off_s1 - 1) + 1 - round_off; // ceil (l - 4)
|
||||
int ymin = (m - 4 + round_off_s1 - 1) + 1 - round_off; // ceil (l - 4)
|
||||
|
||||
// Same here:
|
||||
int xmax = (l - 4 + round_off_s1) - round_off; // floor (l - 4)
|
||||
int ymax = (m - 4 + round_off_s1) - round_off; // floor (m - 4)
|
||||
|
||||
float sum = 0;
|
||||
if (xmax>=0 && ymax>=0 && (xmin<=SIZE_3(gradOutput)-1) && (ymin<=SIZE_2(gradOutput)-1)) {
|
||||
xmin = max(0,xmin);
|
||||
xmax = min(SIZE_3(gradOutput)-1,xmax);
|
||||
|
||||
ymin = max(0,ymin);
|
||||
ymax = min(SIZE_2(gradOutput)-1,ymax);
|
||||
|
||||
for (int p = -4; p <= 4; p++) {
|
||||
for (int o = -4; o <= 4; o++) {
|
||||
// Get rbot1 data:
|
||||
int s2o = o;
|
||||
int s2p = p;
|
||||
int idxbot1 = ((intSample * SIZE_1(rbot0) + (m+s2p)) * SIZE_2(rbot0) + (l+s2o)) * SIZE_3(rbot0) + n;
|
||||
float bot1tmp = rbot1[idxbot1]; // rbot1[l+s2o,m+s2p,n]
|
||||
|
||||
// Index offset for gradOutput in following loops:
|
||||
int op = (p+4) * 9 + (o+4); // index[o,p]
|
||||
int idxopoffset = (intSample * SIZE_1(gradOutput) + op);
|
||||
|
||||
for (int y = ymin; y <= ymax; y++) {
|
||||
for (int x = xmin; x <= xmax; x++) {
|
||||
int idxgradOutput = (idxopoffset * SIZE_2(gradOutput) + y) * SIZE_3(gradOutput) + x; // gradOutput[x,y,o,p]
|
||||
sum += gradOutput[idxgradOutput] * bot1tmp;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
const int sumelems = SIZE_1(gradFirst);
|
||||
const int bot0index = ((n * SIZE_2(gradFirst)) + (m-4)) * SIZE_3(gradFirst) + (l-4);
|
||||
gradFirst[bot0index + intSample*SIZE_1(gradFirst)*SIZE_2(gradFirst)*SIZE_3(gradFirst)] = sum / (float)sumelems;
|
||||
} }
|
||||
'''
|
||||
|
||||
kernel_Correlation_updateGradSecond = '''
|
||||
#define ROUND_OFF 50000
|
||||
|
||||
extern "C" __global__ void kernel_Correlation_updateGradSecond(
|
||||
const int n,
|
||||
const int intSample,
|
||||
const float* rbot0,
|
||||
const float* rbot1,
|
||||
const float* gradOutput,
|
||||
float* gradFirst,
|
||||
float* gradSecond
|
||||
) { for (int intIndex = (blockIdx.x * blockDim.x) + threadIdx.x; intIndex < n; intIndex += blockDim.x * gridDim.x) {
|
||||
int n = intIndex % SIZE_1(gradSecond); // channels
|
||||
int l = (intIndex / SIZE_1(gradSecond)) % SIZE_3(gradSecond) + 4; // w-pos
|
||||
int m = (intIndex / SIZE_1(gradSecond) / SIZE_3(gradSecond)) % SIZE_2(gradSecond) + 4; // h-pos
|
||||
|
||||
// round_off is a trick to enable integer division with ceil, even for negative numbers
|
||||
// We use a large offset, for the inner part not to become negative.
|
||||
const int round_off = ROUND_OFF;
|
||||
const int round_off_s1 = round_off;
|
||||
|
||||
float sum = 0;
|
||||
for (int p = -4; p <= 4; p++) {
|
||||
for (int o = -4; o <= 4; o++) {
|
||||
int s2o = o;
|
||||
int s2p = p;
|
||||
|
||||
//Get X,Y ranges and clamp
|
||||
// We add round_off before_s1 the int division and subtract round_off after it, to ensure the formula matches ceil behavior:
|
||||
int xmin = (l - 4 - s2o + round_off_s1 - 1) + 1 - round_off; // ceil (l - 4 - s2o)
|
||||
int ymin = (m - 4 - s2p + round_off_s1 - 1) + 1 - round_off; // ceil (l - 4 - s2o)
|
||||
|
||||
// Same here:
|
||||
int xmax = (l - 4 - s2o + round_off_s1) - round_off; // floor (l - 4 - s2o)
|
||||
int ymax = (m - 4 - s2p + round_off_s1) - round_off; // floor (m - 4 - s2p)
|
||||
|
||||
if (xmax>=0 && ymax>=0 && (xmin<=SIZE_3(gradOutput)-1) && (ymin<=SIZE_2(gradOutput)-1)) {
|
||||
xmin = max(0,xmin);
|
||||
xmax = min(SIZE_3(gradOutput)-1,xmax);
|
||||
|
||||
ymin = max(0,ymin);
|
||||
ymax = min(SIZE_2(gradOutput)-1,ymax);
|
||||
|
||||
// Get rbot0 data:
|
||||
int idxbot0 = ((intSample * SIZE_1(rbot0) + (m-s2p)) * SIZE_2(rbot0) + (l-s2o)) * SIZE_3(rbot0) + n;
|
||||
float bot0tmp = rbot0[idxbot0]; // rbot1[l+s2o,m+s2p,n]
|
||||
|
||||
// Index offset for gradOutput in following loops:
|
||||
int op = (p+4) * 9 + (o+4); // index[o,p]
|
||||
int idxopoffset = (intSample * SIZE_1(gradOutput) + op);
|
||||
|
||||
for (int y = ymin; y <= ymax; y++) {
|
||||
for (int x = xmin; x <= xmax; x++) {
|
||||
int idxgradOutput = (idxopoffset * SIZE_2(gradOutput) + y) * SIZE_3(gradOutput) + x; // gradOutput[x,y,o,p]
|
||||
sum += gradOutput[idxgradOutput] * bot0tmp;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
const int sumelems = SIZE_1(gradSecond);
|
||||
const int bot1index = ((n * SIZE_2(gradSecond)) + (m-4)) * SIZE_3(gradSecond) + (l-4);
|
||||
gradSecond[bot1index + intSample*SIZE_1(gradSecond)*SIZE_2(gradSecond)*SIZE_3(gradSecond)] = sum / (float)sumelems;
|
||||
} }
|
||||
'''
|
||||
|
||||
def cupy_kernel(strFunction, objVariables):
|
||||
strKernel = globals()[strFunction]
|
||||
|
||||
while True:
|
||||
objMatch = re.search('(SIZE_)([0-4])(\()([^\)]*)(\))', strKernel)
|
||||
|
||||
if objMatch is None:
|
||||
break
|
||||
# end
|
||||
|
||||
intArg = int(objMatch.group(2))
|
||||
|
||||
strTensor = objMatch.group(4)
|
||||
intSizes = objVariables[strTensor].size()
|
||||
|
||||
strKernel = strKernel.replace(objMatch.group(), str(intSizes[intArg]))
|
||||
# end
|
||||
|
||||
while True:
|
||||
objMatch = re.search('(VALUE_)([0-4])(\()([^\)]+)(\))', strKernel)
|
||||
|
||||
if objMatch is None:
|
||||
break
|
||||
# end
|
||||
|
||||
intArgs = int(objMatch.group(2))
|
||||
strArgs = objMatch.group(4).split(',')
|
||||
|
||||
strTensor = strArgs[0]
|
||||
intStrides = objVariables[strTensor].stride()
|
||||
strIndex = [ '((' + strArgs[intArg + 1].replace('{', '(').replace('}', ')').strip() + ')*' + str(intStrides[intArg]) + ')' for intArg in range(intArgs) ]
|
||||
|
||||
strKernel = strKernel.replace(objMatch.group(0), strTensor + '[' + str.join('+', strIndex) + ']')
|
||||
# end
|
||||
|
||||
return strKernel
|
||||
# end
|
||||
|
||||
@cupy.memoize(for_each_device=True)
|
||||
def cupy_launch(strFunction, strKernel):
|
||||
return cupy.RawKernel(strKernel, strFunction)
|
||||
# end
|
||||
|
||||
class _FunctionCorrelation(torch.autograd.Function):
|
||||
@staticmethod
|
||||
def forward(self, first, second):
|
||||
rbot0 = first.new_zeros([ first.shape[0], first.shape[2] + 8, first.shape[3] + 8, first.shape[1] ])
|
||||
rbot1 = first.new_zeros([ first.shape[0], first.shape[2] + 8, first.shape[3] + 8, first.shape[1] ])
|
||||
|
||||
self.save_for_backward(first, second, rbot0, rbot1)
|
||||
|
||||
first = first.contiguous(); assert(first.is_cuda == True)
|
||||
second = second.contiguous(); assert(second.is_cuda == True)
|
||||
|
||||
output = first.new_zeros([ first.shape[0], 81, first.shape[2], first.shape[3] ])
|
||||
|
||||
if first.is_cuda == True:
|
||||
n = first.shape[2] * first.shape[3]
|
||||
cupy_launch('kernel_Correlation_rearrange', cupy_kernel('kernel_Correlation_rearrange', {
|
||||
'input': first,
|
||||
'output': rbot0
|
||||
}))(
|
||||
grid=tuple([ int((n + 16 - 1) / 16), first.shape[1], first.shape[0] ]),
|
||||
block=tuple([ 16, 1, 1 ]),
|
||||
args=[ n, first.data_ptr(), rbot0.data_ptr() ]
|
||||
)
|
||||
|
||||
n = second.shape[2] * second.shape[3]
|
||||
cupy_launch('kernel_Correlation_rearrange', cupy_kernel('kernel_Correlation_rearrange', {
|
||||
'input': second,
|
||||
'output': rbot1
|
||||
}))(
|
||||
grid=tuple([ int((n + 16 - 1) / 16), second.shape[1], second.shape[0] ]),
|
||||
block=tuple([ 16, 1, 1 ]),
|
||||
args=[ n, second.data_ptr(), rbot1.data_ptr() ]
|
||||
)
|
||||
|
||||
n = output.shape[1] * output.shape[2] * output.shape[3]
|
||||
cupy_launch('kernel_Correlation_updateOutput', cupy_kernel('kernel_Correlation_updateOutput', {
|
||||
'rbot0': rbot0,
|
||||
'rbot1': rbot1,
|
||||
'top': output
|
||||
}))(
|
||||
grid=tuple([ output.shape[3], output.shape[2], output.shape[0] ]),
|
||||
block=tuple([ 32, 1, 1 ]),
|
||||
shared_mem=first.shape[1] * 4,
|
||||
args=[ n, rbot0.data_ptr(), rbot1.data_ptr(), output.data_ptr() ]
|
||||
)
|
||||
|
||||
elif first.is_cuda == False:
|
||||
raise NotImplementedError()
|
||||
|
||||
# end
|
||||
|
||||
return output
|
||||
# end
|
||||
|
||||
@staticmethod
|
||||
def backward(self, gradOutput):
|
||||
first, second, rbot0, rbot1 = self.saved_tensors
|
||||
|
||||
gradOutput = gradOutput.contiguous(); assert(gradOutput.is_cuda == True)
|
||||
|
||||
gradFirst = first.new_zeros([ first.shape[0], first.shape[1], first.shape[2], first.shape[3] ]) if self.needs_input_grad[0] == True else None
|
||||
gradSecond = first.new_zeros([ first.shape[0], first.shape[1], first.shape[2], first.shape[3] ]) if self.needs_input_grad[1] == True else None
|
||||
|
||||
if first.is_cuda == True:
|
||||
if gradFirst is not None:
|
||||
for intSample in range(first.shape[0]):
|
||||
n = first.shape[1] * first.shape[2] * first.shape[3]
|
||||
cupy_launch('kernel_Correlation_updateGradFirst', cupy_kernel('kernel_Correlation_updateGradFirst', {
|
||||
'rbot0': rbot0,
|
||||
'rbot1': rbot1,
|
||||
'gradOutput': gradOutput,
|
||||
'gradFirst': gradFirst,
|
||||
'gradSecond': None
|
||||
}))(
|
||||
grid=tuple([ int((n + 512 - 1) / 512), 1, 1 ]),
|
||||
block=tuple([ 512, 1, 1 ]),
|
||||
args=[ n, intSample, rbot0.data_ptr(), rbot1.data_ptr(), gradOutput.data_ptr(), gradFirst.data_ptr(), None ]
|
||||
)
|
||||
# end
|
||||
# end
|
||||
|
||||
if gradSecond is not None:
|
||||
for intSample in range(first.shape[0]):
|
||||
n = first.shape[1] * first.shape[2] * first.shape[3]
|
||||
cupy_launch('kernel_Correlation_updateGradSecond', cupy_kernel('kernel_Correlation_updateGradSecond', {
|
||||
'rbot0': rbot0,
|
||||
'rbot1': rbot1,
|
||||
'gradOutput': gradOutput,
|
||||
'gradFirst': None,
|
||||
'gradSecond': gradSecond
|
||||
}))(
|
||||
grid=tuple([ int((n + 512 - 1) / 512), 1, 1 ]),
|
||||
block=tuple([ 512, 1, 1 ]),
|
||||
args=[ n, intSample, rbot0.data_ptr(), rbot1.data_ptr(), gradOutput.data_ptr(), None, gradSecond.data_ptr() ]
|
||||
)
|
||||
# end
|
||||
# end
|
||||
|
||||
elif first.is_cuda == False:
|
||||
raise NotImplementedError()
|
||||
|
||||
# end
|
||||
|
||||
return gradFirst, gradSecond
|
||||
# end
|
||||
# end
|
||||
|
||||
def FunctionCorrelation(tenFirst, tenSecond):
|
||||
return _FunctionCorrelation.apply(tenFirst, tenSecond)
|
||||
# end
|
||||
|
||||
class ModuleCorrelation(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super(ModuleCorrelation, self).__init__()
|
||||
# end
|
||||
|
||||
def forward(self, tenFirst, tenSecond):
|
||||
return _FunctionCorrelation.apply(tenFirst, tenSecond)
|
||||
# end
|
||||
# end
|
||||
@@ -0,0 +1,308 @@
|
||||
|
||||
from __future__ import absolute_import
|
||||
import os
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from torch.autograd import Variable
|
||||
from .pretrained_networks import vgg16, alexnet, squeezenet
|
||||
import torch.nn
|
||||
import torch.nn.functional as F
|
||||
import torchvision.transforms.functional as TF
|
||||
import cv2
|
||||
|
||||
from .pwcnet import Network as PWCNet
|
||||
from .utils import *
|
||||
|
||||
def spatial_average(in_tens, keepdim=True):
|
||||
return in_tens.mean([2,3],keepdim=keepdim)
|
||||
|
||||
def mw_spatial_average(in_tens, flow, keepdim=True):
|
||||
_,_,h,w = in_tens.shape
|
||||
flow = F.interpolate(flow, (h,w), align_corners=False, mode='bilinear')
|
||||
flow_mag = torch.sqrt(flow[:,0:1]**2 + flow[:,1:2]**2)
|
||||
flow_mag = flow_mag / torch.sum(flow_mag, dim=[1,2,3], keepdim=True)
|
||||
return torch.sum(in_tens*flow_mag, dim=[2,3],keepdim=keepdim)
|
||||
|
||||
|
||||
def mtw_spatial_average(in_tens, flow, texture, keepdim=True):
|
||||
_,_,h,w = in_tens.shape
|
||||
flow = F.interpolate(flow, (h,w), align_corners=False, mode='bilinear')
|
||||
texture = F.interpolate(texture, (h,w), align_corners=False, mode='bilinear')
|
||||
flow_mag = torch.sqrt(flow[:,0:1]**2 + flow[:,1:2]**2)
|
||||
flow_mag = (flow_mag - flow_mag.min()) / (flow_mag.max() - flow_mag.min()) + 1e-6
|
||||
texture = (texture - texture.min()) / (texture.max() - texture.min()) + 1e-6
|
||||
weight = flow_mag / texture
|
||||
weight /= torch.sum(weight)
|
||||
return torch.sum(in_tens*weight, dim=[2,3],keepdim=keepdim)
|
||||
|
||||
|
||||
|
||||
def m2w_spatial_average(in_tens, flow, keepdim=True):
|
||||
_,_,h,w = in_tens.shape
|
||||
flow = F.interpolate(flow, (h,w), align_corners=False, mode='bilinear')
|
||||
flow_mag = flow[:,0:1]**2 + flow[:,1:2]**2 # B,1,H,W
|
||||
flow_mag = flow_mag / torch.sum(flow_mag)
|
||||
return torch.sum(in_tens*flow_mag, dim=[2,3],keepdim=keepdim)
|
||||
|
||||
def upsample(in_tens, out_HW=(64,64)): # assumes scale factor is same for H and W
|
||||
in_H, in_W = in_tens.shape[2], in_tens.shape[3]
|
||||
return nn.Upsample(size=out_HW, mode='bilinear', align_corners=False)(in_tens)
|
||||
|
||||
# Learned perceptual metric
|
||||
class LPIPS(nn.Module):
|
||||
def __init__(self, pretrained=True, net='alex', version='0.1', lpips=True, spatial=False,
|
||||
pnet_rand=False, pnet_tune=False, use_dropout=True, model_path=None, eval_mode=True, verbose=False):
|
||||
# lpips - [True] means with linear calibration on top of base network
|
||||
# pretrained - [True] means load linear weights
|
||||
|
||||
super(LPIPS, self).__init__()
|
||||
if(verbose):
|
||||
print('Setting up [%s] perceptual loss: trunk [%s], v[%s], spatial [%s]'%
|
||||
('LPIPS' if lpips else 'baseline', net, version, 'on' if spatial else 'off'))
|
||||
|
||||
self.pnet_type = net
|
||||
self.pnet_tune = pnet_tune
|
||||
self.pnet_rand = pnet_rand
|
||||
self.spatial = spatial
|
||||
self.lpips = lpips # false means baseline of just averaging all layers
|
||||
self.version = version
|
||||
self.scaling_layer = ScalingLayer()
|
||||
|
||||
if(self.pnet_type in ['vgg','vgg16']):
|
||||
net_type = vgg16
|
||||
self.chns = [64,128,256,512,512]
|
||||
elif(self.pnet_type=='alex'):
|
||||
net_type = alexnet
|
||||
self.chns = [64,192,384,256,256]
|
||||
elif(self.pnet_type=='squeeze'):
|
||||
net_type = squeezenet
|
||||
self.chns = [64,128,256,384,384,512,512]
|
||||
self.L = len(self.chns)
|
||||
|
||||
self.net = net_type(pretrained=not self.pnet_rand, requires_grad=self.pnet_tune)
|
||||
|
||||
if(lpips):
|
||||
self.lin0 = NetLinLayer(self.chns[0], use_dropout=use_dropout)
|
||||
self.lin1 = NetLinLayer(self.chns[1], use_dropout=use_dropout)
|
||||
self.lin2 = NetLinLayer(self.chns[2], use_dropout=use_dropout)
|
||||
self.lin3 = NetLinLayer(self.chns[3], use_dropout=use_dropout)
|
||||
self.lin4 = NetLinLayer(self.chns[4], use_dropout=use_dropout)
|
||||
self.lins = [self.lin0,self.lin1,self.lin2,self.lin3,self.lin4]
|
||||
if(self.pnet_type=='squeeze'): # 7 layers for squeezenet
|
||||
self.lin5 = NetLinLayer(self.chns[5], use_dropout=use_dropout)
|
||||
self.lin6 = NetLinLayer(self.chns[6], use_dropout=use_dropout)
|
||||
self.lins+=[self.lin5,self.lin6]
|
||||
self.lins = nn.ModuleList(self.lins)
|
||||
|
||||
if(pretrained):
|
||||
if(model_path is None):
|
||||
import inspect
|
||||
import os
|
||||
model_path = os.path.abspath(os.path.join(inspect.getfile(self.__init__), '..', 'weights/v%s/%s.pth'%(version,net)))
|
||||
|
||||
if(verbose):
|
||||
print('Loading model from: %s'%model_path)
|
||||
self.load_state_dict(torch.load(model_path, map_location='cpu'), strict=False)
|
||||
|
||||
if(eval_mode):
|
||||
self.eval()
|
||||
|
||||
def forward(self, in0, in1, retPerLayer=False, normalize=False):
|
||||
if normalize: # turn on this flag if input is [0,1] so it can be adjusted to [-1, +1]
|
||||
in0 = 2 * in0 - 1
|
||||
in1 = 2 * in1 - 1
|
||||
|
||||
# v0.0 - original release had a bug, where input was not scaled
|
||||
in0_input, in1_input = (self.scaling_layer(in0), self.scaling_layer(in1)) if self.version=='0.1' else (in0, in1)
|
||||
outs0, outs1 = self.net.forward(in0_input), self.net.forward(in1_input)
|
||||
feats0, feats1, diffs = {}, {}, {}
|
||||
|
||||
for kk in range(self.L):
|
||||
feats0[kk], feats1[kk] = normalize_tensor(outs0[kk]), normalize_tensor(outs1[kk])
|
||||
diffs[kk] = (feats0[kk]-feats1[kk])**2
|
||||
|
||||
if(self.lpips):
|
||||
if(self.spatial):
|
||||
res = [upsample(self.lins[kk](diffs[kk]), out_HW=in0.shape[2:]) for kk in range(self.L)]
|
||||
else:
|
||||
res = [spatial_average(self.lins[kk](diffs[kk]), keepdim=True) for kk in range(self.L)]
|
||||
else:
|
||||
if(self.spatial):
|
||||
res = [upsample(diffs[kk].sum(dim=1,keepdim=True), out_HW=in0.shape[2:]) for kk in range(self.L)]
|
||||
else:
|
||||
res = [spatial_average(diffs[kk].sum(dim=1,keepdim=True), keepdim=True) for kk in range(self.L)]
|
||||
|
||||
# val = res[0]
|
||||
# for l in range(1,self.L):
|
||||
# val += res[l]
|
||||
# print(val)
|
||||
|
||||
# a = spatial_average(self.lins[kk](diffs[kk]), keepdim=True)
|
||||
# b = torch.max(self.lins[kk](feats0[kk]**2))
|
||||
# for kk in range(self.L):
|
||||
# a += spatial_average(self.lins[kk](diffs[kk]), keepdim=True)
|
||||
# b = torch.max(b,torch.max(self.lins[kk](feats0[kk]**2)))
|
||||
# a = a/self.L
|
||||
# from IPython import embed
|
||||
# embed()
|
||||
# return 10*torch.log10(b/a)
|
||||
|
||||
# if(retPerLayer):
|
||||
# return (val, res)
|
||||
# else:
|
||||
return torch.sum(torch.cat(res, 1), dim=(1,2,3), keepdims=False)
|
||||
|
||||
|
||||
class ScalingLayer(nn.Module):
|
||||
def __init__(self):
|
||||
super(ScalingLayer, self).__init__()
|
||||
self.register_buffer('shift', torch.Tensor([-.030,-.088,-.188])[None,:,None,None])
|
||||
self.register_buffer('scale', torch.Tensor([.458,.448,.450])[None,:,None,None])
|
||||
|
||||
def forward(self, inp):
|
||||
return (inp - self.shift) / self.scale
|
||||
|
||||
|
||||
class NetLinLayer(nn.Module):
|
||||
''' A single linear layer which does a 1x1 conv '''
|
||||
def __init__(self, chn_in, chn_out=1, use_dropout=False):
|
||||
super(NetLinLayer, self).__init__()
|
||||
|
||||
layers = [nn.Dropout(),] if(use_dropout) else []
|
||||
layers += [nn.Conv2d(chn_in, chn_out, 1, stride=1, padding=0, bias=False),]
|
||||
self.model = nn.Sequential(*layers)
|
||||
|
||||
def forward(self, x):
|
||||
return self.model(x)
|
||||
|
||||
class Dist2LogitLayer(nn.Module):
|
||||
''' takes 2 distances, puts through fc layers, spits out value between [0,1] (if use_sigmoid is True) '''
|
||||
def __init__(self, chn_mid=32, use_sigmoid=True):
|
||||
super(Dist2LogitLayer, self).__init__()
|
||||
|
||||
layers = [nn.Conv2d(5, chn_mid, 1, stride=1, padding=0, bias=True),]
|
||||
layers += [nn.LeakyReLU(0.2,True),]
|
||||
layers += [nn.Conv2d(chn_mid, chn_mid, 1, stride=1, padding=0, bias=True),]
|
||||
layers += [nn.LeakyReLU(0.2,True),]
|
||||
layers += [nn.Conv2d(chn_mid, 1, 1, stride=1, padding=0, bias=True),]
|
||||
if(use_sigmoid):
|
||||
layers += [nn.Sigmoid(),]
|
||||
self.model = nn.Sequential(*layers)
|
||||
|
||||
def forward(self,d0,d1,eps=0.1):
|
||||
return self.model.forward(torch.cat((d0,d1,d0-d1,d0/(d1+eps),d1/(d0+eps)),dim=1))
|
||||
|
||||
class BCERankingLoss(nn.Module):
|
||||
def __init__(self, chn_mid=32):
|
||||
super(BCERankingLoss, self).__init__()
|
||||
self.net = Dist2LogitLayer(chn_mid=chn_mid)
|
||||
# self.parameters = list(self.net.parameters())
|
||||
self.loss = torch.nn.BCELoss()
|
||||
|
||||
def forward(self, d0, d1, judge):
|
||||
per = (judge+1.)/2.
|
||||
self.logit = self.net.forward(d0,d1)
|
||||
return self.loss(self.logit, per)
|
||||
|
||||
# L2, DSSIM metrics
|
||||
class FakeNet(nn.Module):
|
||||
def __init__(self, use_gpu=True, colorspace='Lab'):
|
||||
super(FakeNet, self).__init__()
|
||||
self.use_gpu = use_gpu
|
||||
self.colorspace = colorspace
|
||||
|
||||
class L2(FakeNet):
|
||||
def forward(self, in0, in1, retPerLayer=None):
|
||||
assert(in0.size()[0]==1) # currently only supports batchSize 1
|
||||
|
||||
if(self.colorspace=='RGB'):
|
||||
(N,C,X,Y) = in0.size()
|
||||
value = torch.mean(torch.mean(torch.mean((in0-in1)**2,dim=1).view(N,1,X,Y),dim=2).view(N,1,1,Y),dim=3).view(N)
|
||||
return value
|
||||
elif(self.colorspace=='Lab'):
|
||||
value = l2(tensor2np(tensor2tensorlab(in0.data,to_norm=False)),
|
||||
tensor2np(tensor2tensorlab(in1.data,to_norm=False)), range=100.).astype('float')
|
||||
ret_var = Variable( torch.Tensor((value,) ) )
|
||||
if(self.use_gpu):
|
||||
ret_var = ret_var.cuda()
|
||||
return ret_var
|
||||
|
||||
class DSSIM(FakeNet):
|
||||
|
||||
def forward(self, in0, in1, retPerLayer=None):
|
||||
assert(in0.size()[0]==1) # currently only supports batchSize 1
|
||||
|
||||
if(self.colorspace=='RGB'):
|
||||
value = dssim(1.*tensor2im(in0.data), 1.*tensor2im(in1.data), range=255.).astype('float')
|
||||
elif(self.colorspace=='Lab'):
|
||||
value = dssim(tensor2np(tensor2tensorlab(in0.data,to_norm=False)),
|
||||
tensor2np(tensor2tensorlab(in1.data,to_norm=False)), range=100.).astype('float')
|
||||
ret_var = Variable( torch.Tensor((value,) ) )
|
||||
if(self.use_gpu):
|
||||
ret_var = ret_var.cuda()
|
||||
return ret_var
|
||||
|
||||
def print_network(net):
|
||||
num_params = 0
|
||||
for param in net.parameters():
|
||||
num_params += param.numel()
|
||||
print('Network',net)
|
||||
print('Total number of parameters: %d' % num_params)
|
||||
|
||||
|
||||
class FloLPIPS(LPIPS):
|
||||
def __init__(self, pretrained=True, net='alex', version='0.1', lpips=True, spatial=False, pnet_rand=False, pnet_tune=False, use_dropout=True, model_path=None, eval_mode=True, verbose=False):
|
||||
super(FloLPIPS, self).__init__(pretrained, net, version, lpips, spatial, pnet_rand, pnet_tune, use_dropout, model_path, eval_mode, verbose)
|
||||
|
||||
def forward(self, in0, in1, flow, retPerLayer=False, normalize=False):
|
||||
if normalize: # turn on this flag if input is [0,1] so it can be adjusted to [-1, +1]
|
||||
in0 = 2 * in0 - 1
|
||||
in1 = 2 * in1 - 1
|
||||
|
||||
in0_input, in1_input = (self.scaling_layer(in0), self.scaling_layer(in1)) if self.version=='0.1' else (in0, in1)
|
||||
outs0, outs1 = self.net.forward(in0_input), self.net.forward(in1_input)
|
||||
feats0, feats1, diffs = {}, {}, {}
|
||||
|
||||
for kk in range(self.L):
|
||||
feats0[kk], feats1[kk] = normalize_tensor(outs0[kk]), normalize_tensor(outs1[kk])
|
||||
diffs[kk] = (feats0[kk]-feats1[kk])**2
|
||||
|
||||
res = [mw_spatial_average(self.lins[kk](diffs[kk]), flow, keepdim=True) for kk in range(self.L)]
|
||||
|
||||
return torch.sum(torch.cat(res, 1), dim=(1,2,3), keepdims=False)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
class Flolpips(nn.Module):
|
||||
def __init__(self):
|
||||
super(Flolpips, self).__init__()
|
||||
self.loss_fn = FloLPIPS(net='alex',version='0.1')
|
||||
self.flownet = PWCNet()
|
||||
|
||||
@torch.no_grad()
|
||||
def forward(self, I0, I1, frame_dis, frame_ref):
|
||||
"""
|
||||
args:
|
||||
I0: first frame of the triplet, shape: [B, C, H, W]
|
||||
I1: third frame of the triplet, shape: [B, C, H, W]
|
||||
frame_dis: prediction of the intermediate frame, shape: [B, C, H, W]
|
||||
frame_ref: ground-truth of the intermediate frame, shape: [B, C, H, W]
|
||||
"""
|
||||
assert I0.size() == I1.size() == frame_dis.size() == frame_ref.size(), \
|
||||
"the 4 input tensors should have same size"
|
||||
|
||||
flow_ref = self.flownet(frame_ref, I0)
|
||||
flow_dis = self.flownet(frame_dis, I0)
|
||||
flow_diff = flow_ref - flow_dis
|
||||
flolpips_wrt_I0 = self.loss_fn.forward(frame_ref, frame_dis, flow_diff, normalize=True)
|
||||
|
||||
flow_ref = self.flownet(frame_ref, I1)
|
||||
flow_dis = self.flownet(frame_dis, I1)
|
||||
flow_diff = flow_ref - flow_dis
|
||||
flolpips_wrt_I1 = self.loss_fn.forward(frame_ref, frame_dis, flow_diff, normalize=True)
|
||||
|
||||
flolpips = (flolpips_wrt_I0 + flolpips_wrt_I1) / 2
|
||||
return flolpips
|
||||
@@ -0,0 +1,180 @@
|
||||
from collections import namedtuple
|
||||
import torch
|
||||
from torchvision import models as tv
|
||||
|
||||
class squeezenet(torch.nn.Module):
|
||||
def __init__(self, requires_grad=False, pretrained=True):
|
||||
super(squeezenet, self).__init__()
|
||||
pretrained_features = tv.squeezenet1_1(pretrained=pretrained).features
|
||||
self.slice1 = torch.nn.Sequential()
|
||||
self.slice2 = torch.nn.Sequential()
|
||||
self.slice3 = torch.nn.Sequential()
|
||||
self.slice4 = torch.nn.Sequential()
|
||||
self.slice5 = torch.nn.Sequential()
|
||||
self.slice6 = torch.nn.Sequential()
|
||||
self.slice7 = torch.nn.Sequential()
|
||||
self.N_slices = 7
|
||||
for x in range(2):
|
||||
self.slice1.add_module(str(x), pretrained_features[x])
|
||||
for x in range(2,5):
|
||||
self.slice2.add_module(str(x), pretrained_features[x])
|
||||
for x in range(5, 8):
|
||||
self.slice3.add_module(str(x), pretrained_features[x])
|
||||
for x in range(8, 10):
|
||||
self.slice4.add_module(str(x), pretrained_features[x])
|
||||
for x in range(10, 11):
|
||||
self.slice5.add_module(str(x), pretrained_features[x])
|
||||
for x in range(11, 12):
|
||||
self.slice6.add_module(str(x), pretrained_features[x])
|
||||
for x in range(12, 13):
|
||||
self.slice7.add_module(str(x), pretrained_features[x])
|
||||
if not requires_grad:
|
||||
for param in self.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
def forward(self, X):
|
||||
h = self.slice1(X)
|
||||
h_relu1 = h
|
||||
h = self.slice2(h)
|
||||
h_relu2 = h
|
||||
h = self.slice3(h)
|
||||
h_relu3 = h
|
||||
h = self.slice4(h)
|
||||
h_relu4 = h
|
||||
h = self.slice5(h)
|
||||
h_relu5 = h
|
||||
h = self.slice6(h)
|
||||
h_relu6 = h
|
||||
h = self.slice7(h)
|
||||
h_relu7 = h
|
||||
vgg_outputs = namedtuple("SqueezeOutputs", ['relu1','relu2','relu3','relu4','relu5','relu6','relu7'])
|
||||
out = vgg_outputs(h_relu1,h_relu2,h_relu3,h_relu4,h_relu5,h_relu6,h_relu7)
|
||||
|
||||
return out
|
||||
|
||||
|
||||
class alexnet(torch.nn.Module):
|
||||
def __init__(self, requires_grad=False, pretrained=True):
|
||||
super(alexnet, self).__init__()
|
||||
alexnet_pretrained_features = tv.alexnet(pretrained=pretrained).features
|
||||
self.slice1 = torch.nn.Sequential()
|
||||
self.slice2 = torch.nn.Sequential()
|
||||
self.slice3 = torch.nn.Sequential()
|
||||
self.slice4 = torch.nn.Sequential()
|
||||
self.slice5 = torch.nn.Sequential()
|
||||
self.N_slices = 5
|
||||
for x in range(2):
|
||||
self.slice1.add_module(str(x), alexnet_pretrained_features[x])
|
||||
for x in range(2, 5):
|
||||
self.slice2.add_module(str(x), alexnet_pretrained_features[x])
|
||||
for x in range(5, 8):
|
||||
self.slice3.add_module(str(x), alexnet_pretrained_features[x])
|
||||
for x in range(8, 10):
|
||||
self.slice4.add_module(str(x), alexnet_pretrained_features[x])
|
||||
for x in range(10, 12):
|
||||
self.slice5.add_module(str(x), alexnet_pretrained_features[x])
|
||||
if not requires_grad:
|
||||
for param in self.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
def forward(self, X):
|
||||
h = self.slice1(X)
|
||||
h_relu1 = h
|
||||
h = self.slice2(h)
|
||||
h_relu2 = h
|
||||
h = self.slice3(h)
|
||||
h_relu3 = h
|
||||
h = self.slice4(h)
|
||||
h_relu4 = h
|
||||
h = self.slice5(h)
|
||||
h_relu5 = h
|
||||
alexnet_outputs = namedtuple("AlexnetOutputs", ['relu1', 'relu2', 'relu3', 'relu4', 'relu5'])
|
||||
out = alexnet_outputs(h_relu1, h_relu2, h_relu3, h_relu4, h_relu5)
|
||||
|
||||
return out
|
||||
|
||||
class vgg16(torch.nn.Module):
|
||||
def __init__(self, requires_grad=False, pretrained=True):
|
||||
super(vgg16, self).__init__()
|
||||
vgg_pretrained_features = tv.vgg16(pretrained=pretrained).features
|
||||
self.slice1 = torch.nn.Sequential()
|
||||
self.slice2 = torch.nn.Sequential()
|
||||
self.slice3 = torch.nn.Sequential()
|
||||
self.slice4 = torch.nn.Sequential()
|
||||
self.slice5 = torch.nn.Sequential()
|
||||
self.N_slices = 5
|
||||
for x in range(4):
|
||||
self.slice1.add_module(str(x), vgg_pretrained_features[x])
|
||||
for x in range(4, 9):
|
||||
self.slice2.add_module(str(x), vgg_pretrained_features[x])
|
||||
for x in range(9, 16):
|
||||
self.slice3.add_module(str(x), vgg_pretrained_features[x])
|
||||
for x in range(16, 23):
|
||||
self.slice4.add_module(str(x), vgg_pretrained_features[x])
|
||||
for x in range(23, 30):
|
||||
self.slice5.add_module(str(x), vgg_pretrained_features[x])
|
||||
if not requires_grad:
|
||||
for param in self.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
def forward(self, X):
|
||||
h = self.slice1(X)
|
||||
h_relu1_2 = h
|
||||
h = self.slice2(h)
|
||||
h_relu2_2 = h
|
||||
h = self.slice3(h)
|
||||
h_relu3_3 = h
|
||||
h = self.slice4(h)
|
||||
h_relu4_3 = h
|
||||
h = self.slice5(h)
|
||||
h_relu5_3 = h
|
||||
vgg_outputs = namedtuple("VggOutputs", ['relu1_2', 'relu2_2', 'relu3_3', 'relu4_3', 'relu5_3'])
|
||||
out = vgg_outputs(h_relu1_2, h_relu2_2, h_relu3_3, h_relu4_3, h_relu5_3)
|
||||
|
||||
return out
|
||||
|
||||
|
||||
|
||||
class resnet(torch.nn.Module):
|
||||
def __init__(self, requires_grad=False, pretrained=True, num=18):
|
||||
super(resnet, self).__init__()
|
||||
if(num==18):
|
||||
self.net = tv.resnet18(pretrained=pretrained)
|
||||
elif(num==34):
|
||||
self.net = tv.resnet34(pretrained=pretrained)
|
||||
elif(num==50):
|
||||
self.net = tv.resnet50(pretrained=pretrained)
|
||||
elif(num==101):
|
||||
self.net = tv.resnet101(pretrained=pretrained)
|
||||
elif(num==152):
|
||||
self.net = tv.resnet152(pretrained=pretrained)
|
||||
self.N_slices = 5
|
||||
|
||||
self.conv1 = self.net.conv1
|
||||
self.bn1 = self.net.bn1
|
||||
self.relu = self.net.relu
|
||||
self.maxpool = self.net.maxpool
|
||||
self.layer1 = self.net.layer1
|
||||
self.layer2 = self.net.layer2
|
||||
self.layer3 = self.net.layer3
|
||||
self.layer4 = self.net.layer4
|
||||
|
||||
def forward(self, X):
|
||||
h = self.conv1(X)
|
||||
h = self.bn1(h)
|
||||
h = self.relu(h)
|
||||
h_relu1 = h
|
||||
h = self.maxpool(h)
|
||||
h = self.layer1(h)
|
||||
h_conv2 = h
|
||||
h = self.layer2(h)
|
||||
h_conv3 = h
|
||||
h = self.layer3(h)
|
||||
h_conv4 = h
|
||||
h = self.layer4(h)
|
||||
h_conv5 = h
|
||||
|
||||
outputs = namedtuple("Outputs", ['relu1','conv2','conv3','conv4','conv5'])
|
||||
out = outputs(h_relu1, h_conv2, h_conv3, h_conv4, h_conv5)
|
||||
|
||||
return out
|
||||
@@ -0,0 +1,344 @@
|
||||
#!/usr/bin/env python
|
||||
|
||||
import torch
|
||||
|
||||
import getopt
|
||||
import math
|
||||
import numpy
|
||||
import os
|
||||
import PIL
|
||||
import PIL.Image
|
||||
import sys
|
||||
|
||||
# try:
|
||||
from .correlation import correlation # the custom cost volume layer
|
||||
# except:
|
||||
# sys.path.insert(0, './correlation'); import correlation # you should consider upgrading python
|
||||
# end
|
||||
|
||||
##########################################################
|
||||
|
||||
# assert(int(str('').join(torch.__version__.split('.')[0:2])) >= 13) # requires at least pytorch version 1.3.0
|
||||
|
||||
# torch.set_grad_enabled(False) # make sure to not compute gradients for computational performance
|
||||
|
||||
# torch.backends.cudnn.enabled = True # make sure to use cudnn for computational performance
|
||||
|
||||
# ##########################################################
|
||||
|
||||
# arguments_strModel = 'default' # 'default', or 'chairs-things'
|
||||
# arguments_strFirst = './images/first.png'
|
||||
# arguments_strSecond = './images/second.png'
|
||||
# arguments_strOut = './out.flo'
|
||||
|
||||
# for strOption, strArgument in getopt.getopt(sys.argv[1:], '', [ strParameter[2:] + '=' for strParameter in sys.argv[1::2] ])[0]:
|
||||
# if strOption == '--model' and strArgument != '': arguments_strModel = strArgument # which model to use
|
||||
# if strOption == '--first' and strArgument != '': arguments_strFirst = strArgument # path to the first frame
|
||||
# if strOption == '--second' and strArgument != '': arguments_strSecond = strArgument # path to the second frame
|
||||
# if strOption == '--out' and strArgument != '': arguments_strOut = strArgument # path to where the output should be stored
|
||||
# end
|
||||
|
||||
##########################################################
|
||||
|
||||
|
||||
|
||||
def backwarp(tenInput, tenFlow):
|
||||
backwarp_tenGrid = {}
|
||||
backwarp_tenPartial = {}
|
||||
if str(tenFlow.shape) not in backwarp_tenGrid:
|
||||
tenHor = torch.linspace(-1.0 + (1.0 / tenFlow.shape[3]), 1.0 - (1.0 / tenFlow.shape[3]), tenFlow.shape[3]).view(1, 1, 1, -1).expand(-1, -1, tenFlow.shape[2], -1)
|
||||
tenVer = torch.linspace(-1.0 + (1.0 / tenFlow.shape[2]), 1.0 - (1.0 / tenFlow.shape[2]), tenFlow.shape[2]).view(1, 1, -1, 1).expand(-1, -1, -1, tenFlow.shape[3])
|
||||
|
||||
backwarp_tenGrid[str(tenFlow.shape)] = torch.cat([ tenHor, tenVer ], 1).cuda()
|
||||
# end
|
||||
|
||||
if str(tenFlow.shape) not in backwarp_tenPartial:
|
||||
backwarp_tenPartial[str(tenFlow.shape)] = tenFlow.new_ones([ tenFlow.shape[0], 1, tenFlow.shape[2], tenFlow.shape[3] ])
|
||||
# end
|
||||
|
||||
tenFlow = torch.cat([ tenFlow[:, 0:1, :, :] / ((tenInput.shape[3] - 1.0) / 2.0), tenFlow[:, 1:2, :, :] / ((tenInput.shape[2] - 1.0) / 2.0) ], 1)
|
||||
tenInput = torch.cat([ tenInput, backwarp_tenPartial[str(tenFlow.shape)] ], 1)
|
||||
|
||||
tenOutput = torch.nn.functional.grid_sample(input=tenInput, grid=(backwarp_tenGrid[str(tenFlow.shape)] + tenFlow).permute(0, 2, 3, 1), mode='bilinear', padding_mode='zeros', align_corners=False)
|
||||
|
||||
tenMask = tenOutput[:, -1:, :, :]; tenMask[tenMask > 0.999] = 1.0; tenMask[tenMask < 1.0] = 0.0
|
||||
|
||||
return tenOutput[:, :-1, :, :] * tenMask
|
||||
# end
|
||||
|
||||
##########################################################
|
||||
|
||||
class Network(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super(Network, self).__init__()
|
||||
|
||||
class Extractor(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super(Extractor, self).__init__()
|
||||
|
||||
self.netOne = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=3, out_channels=16, kernel_size=3, stride=2, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=16, out_channels=16, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=16, out_channels=16, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netTwo = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=16, out_channels=32, kernel_size=3, stride=2, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=32, out_channels=32, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=32, out_channels=32, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netThr = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=32, out_channels=64, kernel_size=3, stride=2, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=64, out_channels=64, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=64, out_channels=64, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netFou = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=64, out_channels=96, kernel_size=3, stride=2, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=96, out_channels=96, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=96, out_channels=96, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netFiv = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=96, out_channels=128, kernel_size=3, stride=2, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=128, out_channels=128, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=128, out_channels=128, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netSix = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=128, out_channels=196, kernel_size=3, stride=2, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=196, out_channels=196, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=196, out_channels=196, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
# end
|
||||
|
||||
def forward(self, tenInput):
|
||||
tenOne = self.netOne(tenInput)
|
||||
tenTwo = self.netTwo(tenOne)
|
||||
tenThr = self.netThr(tenTwo)
|
||||
tenFou = self.netFou(tenThr)
|
||||
tenFiv = self.netFiv(tenFou)
|
||||
tenSix = self.netSix(tenFiv)
|
||||
|
||||
return [ tenOne, tenTwo, tenThr, tenFou, tenFiv, tenSix ]
|
||||
# end
|
||||
# end
|
||||
|
||||
class Decoder(torch.nn.Module):
|
||||
def __init__(self, intLevel):
|
||||
super(Decoder, self).__init__()
|
||||
|
||||
intPrevious = [ None, None, 81 + 32 + 2 + 2, 81 + 64 + 2 + 2, 81 + 96 + 2 + 2, 81 + 128 + 2 + 2, 81, None ][intLevel + 1]
|
||||
intCurrent = [ None, None, 81 + 32 + 2 + 2, 81 + 64 + 2 + 2, 81 + 96 + 2 + 2, 81 + 128 + 2 + 2, 81, None ][intLevel + 0]
|
||||
|
||||
if intLevel < 6: self.netUpflow = torch.nn.ConvTranspose2d(in_channels=2, out_channels=2, kernel_size=4, stride=2, padding=1)
|
||||
if intLevel < 6: self.netUpfeat = torch.nn.ConvTranspose2d(in_channels=intPrevious + 128 + 128 + 96 + 64 + 32, out_channels=2, kernel_size=4, stride=2, padding=1)
|
||||
if intLevel < 6: self.fltBackwarp = [ None, None, None, 5.0, 2.5, 1.25, 0.625, None ][intLevel + 1]
|
||||
|
||||
self.netOne = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=intCurrent, out_channels=128, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netTwo = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=intCurrent + 128, out_channels=128, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netThr = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=intCurrent + 128 + 128, out_channels=96, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netFou = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=intCurrent + 128 + 128 + 96, out_channels=64, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netFiv = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=intCurrent + 128 + 128 + 96 + 64, out_channels=32, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netSix = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=intCurrent + 128 + 128 + 96 + 64 + 32, out_channels=2, kernel_size=3, stride=1, padding=1)
|
||||
)
|
||||
# end
|
||||
|
||||
def forward(self, tenFirst, tenSecond, objPrevious):
|
||||
tenFlow = None
|
||||
tenFeat = None
|
||||
|
||||
if objPrevious is None:
|
||||
tenFlow = None
|
||||
tenFeat = None
|
||||
|
||||
tenVolume = torch.nn.functional.leaky_relu(input=correlation.FunctionCorrelation(tenFirst=tenFirst, tenSecond=tenSecond), negative_slope=0.1, inplace=False)
|
||||
|
||||
tenFeat = torch.cat([ tenVolume ], 1)
|
||||
|
||||
elif objPrevious is not None:
|
||||
tenFlow = self.netUpflow(objPrevious['tenFlow'])
|
||||
tenFeat = self.netUpfeat(objPrevious['tenFeat'])
|
||||
|
||||
tenVolume = torch.nn.functional.leaky_relu(input=correlation.FunctionCorrelation(tenFirst=tenFirst, tenSecond=backwarp(tenInput=tenSecond, tenFlow=tenFlow * self.fltBackwarp)), negative_slope=0.1, inplace=False)
|
||||
|
||||
tenFeat = torch.cat([ tenVolume, tenFirst, tenFlow, tenFeat ], 1)
|
||||
|
||||
# end
|
||||
|
||||
tenFeat = torch.cat([ self.netOne(tenFeat), tenFeat ], 1)
|
||||
tenFeat = torch.cat([ self.netTwo(tenFeat), tenFeat ], 1)
|
||||
tenFeat = torch.cat([ self.netThr(tenFeat), tenFeat ], 1)
|
||||
tenFeat = torch.cat([ self.netFou(tenFeat), tenFeat ], 1)
|
||||
tenFeat = torch.cat([ self.netFiv(tenFeat), tenFeat ], 1)
|
||||
|
||||
tenFlow = self.netSix(tenFeat)
|
||||
|
||||
return {
|
||||
'tenFlow': tenFlow,
|
||||
'tenFeat': tenFeat
|
||||
}
|
||||
# end
|
||||
# end
|
||||
|
||||
class Refiner(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super(Refiner, self).__init__()
|
||||
|
||||
self.netMain = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=81 + 32 + 2 + 2 + 128 + 128 + 96 + 64 + 32, out_channels=128, kernel_size=3, stride=1, padding=1, dilation=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=128, out_channels=128, kernel_size=3, stride=1, padding=2, dilation=2),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=128, out_channels=128, kernel_size=3, stride=1, padding=4, dilation=4),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=128, out_channels=96, kernel_size=3, stride=1, padding=8, dilation=8),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=96, out_channels=64, kernel_size=3, stride=1, padding=16, dilation=16),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=64, out_channels=32, kernel_size=3, stride=1, padding=1, dilation=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=32, out_channels=2, kernel_size=3, stride=1, padding=1, dilation=1)
|
||||
)
|
||||
# end
|
||||
|
||||
def forward(self, tenInput):
|
||||
return self.netMain(tenInput)
|
||||
# end
|
||||
# end
|
||||
|
||||
self.netExtractor = Extractor()
|
||||
|
||||
self.netTwo = Decoder(2)
|
||||
self.netThr = Decoder(3)
|
||||
self.netFou = Decoder(4)
|
||||
self.netFiv = Decoder(5)
|
||||
self.netSix = Decoder(6)
|
||||
|
||||
self.netRefiner = Refiner()
|
||||
|
||||
self.load_state_dict({ strKey.replace('module', 'net'): tenWeight for strKey, tenWeight in torch.hub.load_state_dict_from_url(url='http://content.sniklaus.com/github/pytorch-pwc/network-' + 'default' + '.pytorch').items() })
|
||||
# end
|
||||
|
||||
def forward(self, tenFirst, tenSecond):
|
||||
intWidth = tenFirst.shape[3]
|
||||
intHeight = tenFirst.shape[2]
|
||||
|
||||
intPreprocessedWidth = int(math.floor(math.ceil(intWidth / 64.0) * 64.0))
|
||||
intPreprocessedHeight = int(math.floor(math.ceil(intHeight / 64.0) * 64.0))
|
||||
|
||||
tenPreprocessedFirst = torch.nn.functional.interpolate(input=tenFirst, size=(intPreprocessedHeight, intPreprocessedWidth), mode='bilinear', align_corners=False)
|
||||
tenPreprocessedSecond = torch.nn.functional.interpolate(input=tenSecond, size=(intPreprocessedHeight, intPreprocessedWidth), mode='bilinear', align_corners=False)
|
||||
|
||||
tenFirst = self.netExtractor(tenPreprocessedFirst)
|
||||
tenSecond = self.netExtractor(tenPreprocessedSecond)
|
||||
|
||||
|
||||
objEstimate = self.netSix(tenFirst[-1], tenSecond[-1], None)
|
||||
objEstimate = self.netFiv(tenFirst[-2], tenSecond[-2], objEstimate)
|
||||
objEstimate = self.netFou(tenFirst[-3], tenSecond[-3], objEstimate)
|
||||
objEstimate = self.netThr(tenFirst[-4], tenSecond[-4], objEstimate)
|
||||
objEstimate = self.netTwo(tenFirst[-5], tenSecond[-5], objEstimate)
|
||||
|
||||
tenFlow = objEstimate['tenFlow'] + self.netRefiner(objEstimate['tenFeat'])
|
||||
tenFlow = 20.0 * torch.nn.functional.interpolate(input=tenFlow, size=(intHeight, intWidth), mode='bilinear', align_corners=False)
|
||||
tenFlow[:, 0, :, :] *= float(intWidth) / float(intPreprocessedWidth)
|
||||
tenFlow[:, 1, :, :] *= float(intHeight) / float(intPreprocessedHeight)
|
||||
|
||||
return tenFlow
|
||||
# end
|
||||
# end
|
||||
|
||||
netNetwork = None
|
||||
|
||||
##########################################################
|
||||
|
||||
def estimate(tenFirst, tenSecond):
|
||||
global netNetwork
|
||||
|
||||
if netNetwork is None:
|
||||
netNetwork = Network().cuda().eval()
|
||||
# end
|
||||
|
||||
assert(tenFirst.shape[1] == tenSecond.shape[1])
|
||||
assert(tenFirst.shape[2] == tenSecond.shape[2])
|
||||
|
||||
intWidth = tenFirst.shape[2]
|
||||
intHeight = tenFirst.shape[1]
|
||||
|
||||
assert(intWidth == 1024) # remember that there is no guarantee for correctness, comment this line out if you acknowledge this and want to continue
|
||||
assert(intHeight == 436) # remember that there is no guarantee for correctness, comment this line out if you acknowledge this and want to continue
|
||||
|
||||
tenPreprocessedFirst = tenFirst.cuda().view(1, 3, intHeight, intWidth)
|
||||
tenPreprocessedSecond = tenSecond.cuda().view(1, 3, intHeight, intWidth)
|
||||
|
||||
intPreprocessedWidth = int(math.floor(math.ceil(intWidth / 64.0) * 64.0))
|
||||
intPreprocessedHeight = int(math.floor(math.ceil(intHeight / 64.0) * 64.0))
|
||||
|
||||
tenPreprocessedFirst = torch.nn.functional.interpolate(input=tenPreprocessedFirst, size=(intPreprocessedHeight, intPreprocessedWidth), mode='bilinear', align_corners=False)
|
||||
tenPreprocessedSecond = torch.nn.functional.interpolate(input=tenPreprocessedSecond, size=(intPreprocessedHeight, intPreprocessedWidth), mode='bilinear', align_corners=False)
|
||||
|
||||
tenFlow = 20.0 * torch.nn.functional.interpolate(input=netNetwork(tenPreprocessedFirst, tenPreprocessedSecond), size=(intHeight, intWidth), mode='bilinear', align_corners=False)
|
||||
|
||||
tenFlow[:, 0, :, :] *= float(intWidth) / float(intPreprocessedWidth)
|
||||
tenFlow[:, 1, :, :] *= float(intHeight) / float(intPreprocessedHeight)
|
||||
|
||||
return tenFlow[0, :, :, :].cpu()
|
||||
# end
|
||||
|
||||
##########################################################
|
||||
|
||||
# if __name__ == '__main__':
|
||||
# tenFirst = torch.FloatTensor(numpy.ascontiguousarray(numpy.array(PIL.Image.open(arguments_strFirst))[:, :, ::-1].transpose(2, 0, 1).astype(numpy.float32) * (1.0 / 255.0)))
|
||||
# tenSecond = torch.FloatTensor(numpy.ascontiguousarray(numpy.array(PIL.Image.open(arguments_strSecond))[:, :, ::-1].transpose(2, 0, 1).astype(numpy.float32) * (1.0 / 255.0)))
|
||||
|
||||
# tenOutput = estimate(tenFirst, tenSecond)
|
||||
|
||||
# objOutput = open(arguments_strOut, 'wb')
|
||||
|
||||
# numpy.array([ 80, 73, 69, 72 ], numpy.uint8).tofile(objOutput)
|
||||
# numpy.array([ tenOutput.shape[2], tenOutput.shape[1] ], numpy.int32).tofile(objOutput)
|
||||
# numpy.array(tenOutput.numpy().transpose(1, 2, 0), numpy.float32).tofile(objOutput)
|
||||
|
||||
# objOutput.close()
|
||||
# end
|
||||
@@ -0,0 +1,95 @@
|
||||
import numpy as np
|
||||
import cv2
|
||||
import torch
|
||||
|
||||
|
||||
def normalize_tensor(in_feat,eps=1e-10):
|
||||
norm_factor = torch.sqrt(torch.sum(in_feat**2,dim=1,keepdim=True))
|
||||
return in_feat/(norm_factor+eps)
|
||||
|
||||
def l2(p0, p1, range=255.):
|
||||
return .5*np.mean((p0 / range - p1 / range)**2)
|
||||
|
||||
def dssim(p0, p1, range=255.):
|
||||
from skimage.measure import compare_ssim
|
||||
return (1 - compare_ssim(p0, p1, data_range=range, multichannel=True)) / 2.
|
||||
|
||||
def tensor2im(image_tensor, imtype=np.uint8, cent=1., factor=255./2.):
|
||||
image_numpy = image_tensor[0].cpu().float().numpy()
|
||||
image_numpy = (np.transpose(image_numpy, (1, 2, 0)) + cent) * factor
|
||||
return image_numpy.astype(imtype)
|
||||
|
||||
def tensor2np(tensor_obj):
|
||||
# change dimension of a tensor object into a numpy array
|
||||
return tensor_obj[0].cpu().float().numpy().transpose((1,2,0))
|
||||
|
||||
def np2tensor(np_obj):
|
||||
# change dimenion of np array into tensor array
|
||||
return torch.Tensor(np_obj[:, :, :, np.newaxis].transpose((3, 2, 0, 1)))
|
||||
|
||||
def tensor2tensorlab(image_tensor,to_norm=True,mc_only=False):
|
||||
# image tensor to lab tensor
|
||||
from skimage import color
|
||||
|
||||
img = tensor2im(image_tensor)
|
||||
img_lab = color.rgb2lab(img)
|
||||
if(mc_only):
|
||||
img_lab[:,:,0] = img_lab[:,:,0]-50
|
||||
if(to_norm and not mc_only):
|
||||
img_lab[:,:,0] = img_lab[:,:,0]-50
|
||||
img_lab = img_lab/100.
|
||||
|
||||
return np2tensor(img_lab)
|
||||
|
||||
def read_frame_yuv2rgb(stream, width, height, iFrame, bit_depth, pix_fmt='420'):
|
||||
if pix_fmt == '420':
|
||||
multiplier = 1
|
||||
uv_factor = 2
|
||||
elif pix_fmt == '444':
|
||||
multiplier = 2
|
||||
uv_factor = 1
|
||||
else:
|
||||
print('Pixel format {} is not supported'.format(pix_fmt))
|
||||
return
|
||||
|
||||
if bit_depth == 8:
|
||||
datatype = np.uint8
|
||||
stream.seek(iFrame*1.5*width*height*multiplier)
|
||||
Y = np.fromfile(stream, dtype=datatype, count=width*height).reshape((height, width))
|
||||
|
||||
# read chroma samples and upsample since original is 4:2:0 sampling
|
||||
U = np.fromfile(stream, dtype=datatype, count=(width//uv_factor)*(height//uv_factor)).\
|
||||
reshape((height//uv_factor, width//uv_factor))
|
||||
V = np.fromfile(stream, dtype=datatype, count=(width//uv_factor)*(height//uv_factor)).\
|
||||
reshape((height//uv_factor, width//uv_factor))
|
||||
|
||||
else:
|
||||
datatype = np.uint16
|
||||
stream.seek(iFrame*3*width*height*multiplier)
|
||||
Y = np.fromfile(stream, dtype=datatype, count=width*height).reshape((height, width))
|
||||
|
||||
U = np.fromfile(stream, dtype=datatype, count=(width//uv_factor)*(height//uv_factor)).\
|
||||
reshape((height//uv_factor, width//uv_factor))
|
||||
V = np.fromfile(stream, dtype=datatype, count=(width//uv_factor)*(height//uv_factor)).\
|
||||
reshape((height//uv_factor, width//uv_factor))
|
||||
|
||||
if pix_fmt == '420':
|
||||
yuv = np.empty((height*3//2, width), dtype=datatype)
|
||||
yuv[0:height,:] = Y
|
||||
|
||||
yuv[height:height+height//4,:] = U.reshape(-1, width)
|
||||
yuv[height+height//4:,:] = V.reshape(-1, width)
|
||||
|
||||
if bit_depth != 8:
|
||||
yuv = (yuv/(2**bit_depth-1)*255).astype(np.uint8)
|
||||
|
||||
#convert to rgb
|
||||
rgb = cv2.cvtColor(yuv, cv2.COLOR_YUV2RGB_I420)
|
||||
|
||||
else:
|
||||
yvu = np.stack([Y,V,U],axis=2)
|
||||
if bit_depth != 8:
|
||||
yvu = (yvu/(2**bit_depth-1)*255).astype(np.uint8)
|
||||
rgb = cv2.cvtColor(yvu, cv2.COLOR_YCrCb2RGB)
|
||||
|
||||
return rgb
|
||||
@@ -0,0 +1,90 @@
|
||||
import torch
|
||||
import os
|
||||
import math
|
||||
import torch.nn.functional as F
|
||||
|
||||
# https://github.com/universome/fvd-comparison
|
||||
|
||||
|
||||
def load_i3d_pretrained(device=torch.device('cpu')):
|
||||
i3D_WEIGHTS_URL = "https://www.dropbox.com/s/ge9e5ujwgetktms/i3d_torchscript.pt"
|
||||
filepath = os.path.join(os.path.dirname(os.path.abspath(__file__)), 'i3d_torchscript.pt')
|
||||
print(filepath)
|
||||
if not os.path.exists(filepath):
|
||||
print(f"preparing for download {i3D_WEIGHTS_URL}, you can download it by yourself.")
|
||||
os.system(f"wget {i3D_WEIGHTS_URL} -O {filepath}")
|
||||
i3d = torch.jit.load(filepath).eval().to(device)
|
||||
i3d = torch.nn.DataParallel(i3d)
|
||||
return i3d
|
||||
|
||||
|
||||
def get_feats(videos, detector, device, bs=10):
|
||||
# videos : torch.tensor BCTHW [0, 1]
|
||||
detector_kwargs = dict(rescale=False, resize=False, return_features=True) # Return raw features before the softmax layer.
|
||||
feats = np.empty((0, 400))
|
||||
with torch.no_grad():
|
||||
for i in range((len(videos)-1)//bs + 1):
|
||||
feats = np.vstack([feats, detector(torch.stack([preprocess_single(video) for video in videos[i*bs:(i+1)*bs]]).to(device), **detector_kwargs).detach().cpu().numpy()])
|
||||
return feats
|
||||
|
||||
|
||||
def get_fvd_feats(videos, i3d, device, bs=10):
|
||||
# videos in [0, 1] as torch tensor BCTHW
|
||||
# videos = [preprocess_single(video) for video in videos]
|
||||
embeddings = get_feats(videos, i3d, device, bs)
|
||||
return embeddings
|
||||
|
||||
|
||||
def preprocess_single(video, resolution=224, sequence_length=None):
|
||||
# video: CTHW, [0, 1]
|
||||
c, t, h, w = video.shape
|
||||
|
||||
# temporal crop
|
||||
if sequence_length is not None:
|
||||
assert sequence_length <= t
|
||||
video = video[:, :sequence_length]
|
||||
|
||||
# scale shorter side to resolution
|
||||
scale = resolution / min(h, w)
|
||||
if h < w:
|
||||
target_size = (resolution, math.ceil(w * scale))
|
||||
else:
|
||||
target_size = (math.ceil(h * scale), resolution)
|
||||
video = F.interpolate(video, size=target_size, mode='bilinear', align_corners=False)
|
||||
|
||||
# center crop
|
||||
c, t, h, w = video.shape
|
||||
w_start = (w - resolution) // 2
|
||||
h_start = (h - resolution) // 2
|
||||
video = video[:, :, h_start:h_start + resolution, w_start:w_start + resolution]
|
||||
|
||||
# [0, 1] -> [-1, 1]
|
||||
video = (video - 0.5) * 2
|
||||
|
||||
return video.contiguous()
|
||||
|
||||
|
||||
"""
|
||||
Copy-pasted from https://github.com/cvpr2022-stylegan-v/stylegan-v/blob/main/src/metrics/frechet_video_distance.py
|
||||
"""
|
||||
from typing import Tuple
|
||||
from scipy.linalg import sqrtm
|
||||
import numpy as np
|
||||
|
||||
|
||||
def compute_stats(feats: np.ndarray) -> Tuple[np.ndarray, np.ndarray]:
|
||||
mu = feats.mean(axis=0) # [d]
|
||||
sigma = np.cov(feats, rowvar=False) # [d, d]
|
||||
return mu, sigma
|
||||
|
||||
|
||||
def frechet_distance(feats_fake: np.ndarray, feats_real: np.ndarray) -> float:
|
||||
mu_gen, sigma_gen = compute_stats(feats_fake)
|
||||
mu_real, sigma_real = compute_stats(feats_real)
|
||||
m = np.square(mu_gen - mu_real).sum()
|
||||
if feats_fake.shape[0]>1:
|
||||
s, _ = sqrtm(np.dot(sigma_gen, sigma_real), disp=False) # pylint: disable=no-member
|
||||
fid = np.real(m + np.trace(sigma_gen + sigma_real - s * 2))
|
||||
else:
|
||||
fid = np.real(m)
|
||||
return float(fid)
|
||||
@@ -0,0 +1,137 @@
|
||||
import torch
|
||||
import os
|
||||
import math
|
||||
import torch.nn.functional as F
|
||||
import numpy as np
|
||||
import einops
|
||||
|
||||
def load_i3d_pretrained(device=torch.device('cpu')):
|
||||
i3D_WEIGHTS_URL = "https://onedrive.live.com/download?cid=78EEF3EB6AE7DBCB&resid=78EEF3EB6AE7DBCB%21199&authkey=AApKdFHPXzWLNyI"
|
||||
filepath = os.path.join(os.path.dirname(os.path.abspath(__file__)), 'i3d_pretrained_400.pt')
|
||||
print(filepath)
|
||||
if not os.path.exists(filepath):
|
||||
print(f"preparing for download {i3D_WEIGHTS_URL}, you can download it by yourself.")
|
||||
os.system(f"wget {i3D_WEIGHTS_URL} -O {filepath}")
|
||||
from .pytorch_i3d import InceptionI3d
|
||||
i3d = InceptionI3d(400, in_channels=3).eval().to(device)
|
||||
i3d.load_state_dict(torch.load(filepath, map_location=device))
|
||||
i3d = torch.nn.DataParallel(i3d)
|
||||
return i3d
|
||||
|
||||
def preprocess_single(video, resolution, sequence_length=None):
|
||||
# video: THWC, {0, ..., 255}
|
||||
video = video.permute(0, 3, 1, 2).float() / 255. # TCHW
|
||||
t, c, h, w = video.shape
|
||||
|
||||
# temporal crop
|
||||
if sequence_length is not None:
|
||||
assert sequence_length <= t
|
||||
video = video[:sequence_length]
|
||||
|
||||
# scale shorter side to resolution
|
||||
scale = resolution / min(h, w)
|
||||
if h < w:
|
||||
target_size = (resolution, math.ceil(w * scale))
|
||||
else:
|
||||
target_size = (math.ceil(h * scale), resolution)
|
||||
video = F.interpolate(video, size=target_size, mode='bilinear',
|
||||
align_corners=False)
|
||||
|
||||
# center crop
|
||||
t, c, h, w = video.shape
|
||||
w_start = (w - resolution) // 2
|
||||
h_start = (h - resolution) // 2
|
||||
video = video[:, :, h_start:h_start + resolution, w_start:w_start + resolution]
|
||||
video = video.permute(1, 0, 2, 3).contiguous() # CTHW
|
||||
|
||||
video -= 0.5
|
||||
|
||||
return video
|
||||
|
||||
def preprocess(videos, target_resolution=224):
|
||||
# we should tras videos in [0-1] [b c t h w] as th.float
|
||||
# -> videos in {0, ..., 255} [b t h w c] as np.uint8 array
|
||||
videos = einops.rearrange(videos, 'b c t h w -> b t h w c')
|
||||
videos = (videos*255).numpy().astype(np.uint8)
|
||||
|
||||
b, t, h, w, c = videos.shape
|
||||
videos = torch.from_numpy(videos)
|
||||
videos = torch.stack([preprocess_single(video, target_resolution) for video in videos])
|
||||
return videos * 2 # [-0.5, 0.5] -> [-1, 1]
|
||||
|
||||
def get_fvd_logits(videos, i3d, device, bs=10):
|
||||
videos = preprocess(videos)
|
||||
embeddings = get_logits(i3d, videos, device, bs=10)
|
||||
return embeddings
|
||||
|
||||
# https://github.com/tensorflow/gan/blob/de4b8da3853058ea380a6152bd3bd454013bf619/tensorflow_gan/python/eval/classifier_metrics.py#L161
|
||||
def _symmetric_matrix_square_root(mat, eps=1e-10):
|
||||
u, s, v = torch.svd(mat)
|
||||
si = torch.where(s < eps, s, torch.sqrt(s))
|
||||
return torch.matmul(torch.matmul(u, torch.diag(si)), v.t())
|
||||
|
||||
# https://github.com/tensorflow/gan/blob/de4b8da3853058ea380a6152bd3bd454013bf619/tensorflow_gan/python/eval/classifier_metrics.py#L400
|
||||
def trace_sqrt_product(sigma, sigma_v):
|
||||
sqrt_sigma = _symmetric_matrix_square_root(sigma)
|
||||
sqrt_a_sigmav_a = torch.matmul(sqrt_sigma, torch.matmul(sigma_v, sqrt_sigma))
|
||||
return torch.trace(_symmetric_matrix_square_root(sqrt_a_sigmav_a))
|
||||
|
||||
# https://discuss.pytorch.org/t/covariance-and-gradient-support/16217/2
|
||||
def cov(m, rowvar=False):
|
||||
'''Estimate a covariance matrix given data.
|
||||
|
||||
Covariance indicates the level to which two variables vary together.
|
||||
If we examine N-dimensional samples, `X = [x_1, x_2, ... x_N]^T`,
|
||||
then the covariance matrix element `C_{ij}` is the covariance of
|
||||
`x_i` and `x_j`. The element `C_{ii}` is the variance of `x_i`.
|
||||
|
||||
Args:
|
||||
m: A 1-D or 2-D array containing multiple variables and observations.
|
||||
Each row of `m` represents a variable, and each column a single
|
||||
observation of all those variables.
|
||||
rowvar: If `rowvar` is True, then each row represents a
|
||||
variable, with observations in the columns. Otherwise, the
|
||||
relationship is transposed: each column represents a variable,
|
||||
while the rows contain observations.
|
||||
|
||||
Returns:
|
||||
The covariance matrix of the variables.
|
||||
'''
|
||||
if m.dim() > 2:
|
||||
raise ValueError('m has more than 2 dimensions')
|
||||
if m.dim() < 2:
|
||||
m = m.view(1, -1)
|
||||
if not rowvar and m.size(0) != 1:
|
||||
m = m.t()
|
||||
|
||||
fact = 1.0 / (m.size(1) - 1) # unbiased estimate
|
||||
m -= torch.mean(m, dim=1, keepdim=True)
|
||||
mt = m.t() # if complex: mt = m.t().conj()
|
||||
return fact * m.matmul(mt).squeeze()
|
||||
|
||||
|
||||
def frechet_distance(x1, x2):
|
||||
x1 = x1.flatten(start_dim=1)
|
||||
x2 = x2.flatten(start_dim=1)
|
||||
m, m_w = x1.mean(dim=0), x2.mean(dim=0)
|
||||
sigma, sigma_w = cov(x1, rowvar=False), cov(x2, rowvar=False)
|
||||
mean = torch.sum((m - m_w) ** 2)
|
||||
if x1.shape[0]>1:
|
||||
sqrt_trace_component = trace_sqrt_product(sigma, sigma_w)
|
||||
trace = torch.trace(sigma + sigma_w) - 2.0 * sqrt_trace_component
|
||||
fd = trace + mean
|
||||
else:
|
||||
fd = np.real(mean)
|
||||
return float(fd)
|
||||
|
||||
|
||||
def get_logits(i3d, videos, device, bs=10):
|
||||
# assert videos.shape[0] % 16 == 0
|
||||
with torch.no_grad():
|
||||
logits = []
|
||||
for i in range(0, videos.shape[0], bs):
|
||||
batch = videos[i:i + bs].to(device)
|
||||
# logits.append(i3d.module.extract_features(batch)) # wrong
|
||||
logits.append(i3d(batch)) # right
|
||||
logits = torch.cat(logits, dim=0)
|
||||
return logits
|
||||
@@ -0,0 +1,322 @@
|
||||
# Original code from https://github.com/piergiaj/pytorch-i3d
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
import numpy as np
|
||||
|
||||
class MaxPool3dSamePadding(nn.MaxPool3d):
|
||||
|
||||
def compute_pad(self, dim, s):
|
||||
if s % self.stride[dim] == 0:
|
||||
return max(self.kernel_size[dim] - self.stride[dim], 0)
|
||||
else:
|
||||
return max(self.kernel_size[dim] - (s % self.stride[dim]), 0)
|
||||
|
||||
def forward(self, x):
|
||||
# compute 'same' padding
|
||||
(batch, channel, t, h, w) = x.size()
|
||||
out_t = np.ceil(float(t) / float(self.stride[0]))
|
||||
out_h = np.ceil(float(h) / float(self.stride[1]))
|
||||
out_w = np.ceil(float(w) / float(self.stride[2]))
|
||||
pad_t = self.compute_pad(0, t)
|
||||
pad_h = self.compute_pad(1, h)
|
||||
pad_w = self.compute_pad(2, w)
|
||||
|
||||
pad_t_f = pad_t // 2
|
||||
pad_t_b = pad_t - pad_t_f
|
||||
pad_h_f = pad_h // 2
|
||||
pad_h_b = pad_h - pad_h_f
|
||||
pad_w_f = pad_w // 2
|
||||
pad_w_b = pad_w - pad_w_f
|
||||
|
||||
pad = (pad_w_f, pad_w_b, pad_h_f, pad_h_b, pad_t_f, pad_t_b)
|
||||
x = F.pad(x, pad)
|
||||
return super(MaxPool3dSamePadding, self).forward(x)
|
||||
|
||||
|
||||
class Unit3D(nn.Module):
|
||||
|
||||
def __init__(self, in_channels,
|
||||
output_channels,
|
||||
kernel_shape=(1, 1, 1),
|
||||
stride=(1, 1, 1),
|
||||
padding=0,
|
||||
activation_fn=F.relu,
|
||||
use_batch_norm=True,
|
||||
use_bias=False,
|
||||
name='unit_3d'):
|
||||
|
||||
"""Initializes Unit3D module."""
|
||||
super(Unit3D, self).__init__()
|
||||
|
||||
self._output_channels = output_channels
|
||||
self._kernel_shape = kernel_shape
|
||||
self._stride = stride
|
||||
self._use_batch_norm = use_batch_norm
|
||||
self._activation_fn = activation_fn
|
||||
self._use_bias = use_bias
|
||||
self.name = name
|
||||
self.padding = padding
|
||||
|
||||
self.conv3d = nn.Conv3d(in_channels=in_channels,
|
||||
out_channels=self._output_channels,
|
||||
kernel_size=self._kernel_shape,
|
||||
stride=self._stride,
|
||||
padding=0, # we always want padding to be 0 here. We will dynamically pad based on input size in forward function
|
||||
bias=self._use_bias)
|
||||
|
||||
if self._use_batch_norm:
|
||||
self.bn = nn.BatchNorm3d(self._output_channels, eps=1e-5, momentum=0.001)
|
||||
|
||||
def compute_pad(self, dim, s):
|
||||
if s % self._stride[dim] == 0:
|
||||
return max(self._kernel_shape[dim] - self._stride[dim], 0)
|
||||
else:
|
||||
return max(self._kernel_shape[dim] - (s % self._stride[dim]), 0)
|
||||
|
||||
|
||||
def forward(self, x):
|
||||
# compute 'same' padding
|
||||
(batch, channel, t, h, w) = x.size()
|
||||
out_t = np.ceil(float(t) / float(self._stride[0]))
|
||||
out_h = np.ceil(float(h) / float(self._stride[1]))
|
||||
out_w = np.ceil(float(w) / float(self._stride[2]))
|
||||
pad_t = self.compute_pad(0, t)
|
||||
pad_h = self.compute_pad(1, h)
|
||||
pad_w = self.compute_pad(2, w)
|
||||
|
||||
pad_t_f = pad_t // 2
|
||||
pad_t_b = pad_t - pad_t_f
|
||||
pad_h_f = pad_h // 2
|
||||
pad_h_b = pad_h - pad_h_f
|
||||
pad_w_f = pad_w // 2
|
||||
pad_w_b = pad_w - pad_w_f
|
||||
|
||||
pad = (pad_w_f, pad_w_b, pad_h_f, pad_h_b, pad_t_f, pad_t_b)
|
||||
x = F.pad(x, pad)
|
||||
|
||||
x = self.conv3d(x)
|
||||
if self._use_batch_norm:
|
||||
x = self.bn(x)
|
||||
if self._activation_fn is not None:
|
||||
x = self._activation_fn(x)
|
||||
return x
|
||||
|
||||
|
||||
|
||||
class InceptionModule(nn.Module):
|
||||
def __init__(self, in_channels, out_channels, name):
|
||||
super(InceptionModule, self).__init__()
|
||||
|
||||
self.b0 = Unit3D(in_channels=in_channels, output_channels=out_channels[0], kernel_shape=[1, 1, 1], padding=0,
|
||||
name=name+'/Branch_0/Conv3d_0a_1x1')
|
||||
self.b1a = Unit3D(in_channels=in_channels, output_channels=out_channels[1], kernel_shape=[1, 1, 1], padding=0,
|
||||
name=name+'/Branch_1/Conv3d_0a_1x1')
|
||||
self.b1b = Unit3D(in_channels=out_channels[1], output_channels=out_channels[2], kernel_shape=[3, 3, 3],
|
||||
name=name+'/Branch_1/Conv3d_0b_3x3')
|
||||
self.b2a = Unit3D(in_channels=in_channels, output_channels=out_channels[3], kernel_shape=[1, 1, 1], padding=0,
|
||||
name=name+'/Branch_2/Conv3d_0a_1x1')
|
||||
self.b2b = Unit3D(in_channels=out_channels[3], output_channels=out_channels[4], kernel_shape=[3, 3, 3],
|
||||
name=name+'/Branch_2/Conv3d_0b_3x3')
|
||||
self.b3a = MaxPool3dSamePadding(kernel_size=[3, 3, 3],
|
||||
stride=(1, 1, 1), padding=0)
|
||||
self.b3b = Unit3D(in_channels=in_channels, output_channels=out_channels[5], kernel_shape=[1, 1, 1], padding=0,
|
||||
name=name+'/Branch_3/Conv3d_0b_1x1')
|
||||
self.name = name
|
||||
|
||||
def forward(self, x):
|
||||
b0 = self.b0(x)
|
||||
b1 = self.b1b(self.b1a(x))
|
||||
b2 = self.b2b(self.b2a(x))
|
||||
b3 = self.b3b(self.b3a(x))
|
||||
return torch.cat([b0,b1,b2,b3], dim=1)
|
||||
|
||||
|
||||
class InceptionI3d(nn.Module):
|
||||
"""Inception-v1 I3D architecture.
|
||||
The model is introduced in:
|
||||
Quo Vadis, Action Recognition? A New Model and the Kinetics Dataset
|
||||
Joao Carreira, Andrew Zisserman
|
||||
https://arxiv.org/pdf/1705.07750v1.pdf.
|
||||
See also the Inception architecture, introduced in:
|
||||
Going deeper with convolutions
|
||||
Christian Szegedy, Wei Liu, Yangqing Jia, Pierre Sermanet, Scott Reed,
|
||||
Dragomir Anguelov, Dumitru Erhan, Vincent Vanhoucke, Andrew Rabinovich.
|
||||
http://arxiv.org/pdf/1409.4842v1.pdf.
|
||||
"""
|
||||
|
||||
# Endpoints of the model in order. During construction, all the endpoints up
|
||||
# to a designated `final_endpoint` are returned in a dictionary as the
|
||||
# second return value.
|
||||
VALID_ENDPOINTS = (
|
||||
'Conv3d_1a_7x7',
|
||||
'MaxPool3d_2a_3x3',
|
||||
'Conv3d_2b_1x1',
|
||||
'Conv3d_2c_3x3',
|
||||
'MaxPool3d_3a_3x3',
|
||||
'Mixed_3b',
|
||||
'Mixed_3c',
|
||||
'MaxPool3d_4a_3x3',
|
||||
'Mixed_4b',
|
||||
'Mixed_4c',
|
||||
'Mixed_4d',
|
||||
'Mixed_4e',
|
||||
'Mixed_4f',
|
||||
'MaxPool3d_5a_2x2',
|
||||
'Mixed_5b',
|
||||
'Mixed_5c',
|
||||
'Logits',
|
||||
'Predictions',
|
||||
)
|
||||
|
||||
def __init__(self, num_classes=400, spatial_squeeze=True,
|
||||
final_endpoint='Logits', name='inception_i3d', in_channels=3, dropout_keep_prob=0.5):
|
||||
"""Initializes I3D model instance.
|
||||
Args:
|
||||
num_classes: The number of outputs in the logit layer (default 400, which
|
||||
matches the Kinetics dataset).
|
||||
spatial_squeeze: Whether to squeeze the spatial dimensions for the logits
|
||||
before returning (default True).
|
||||
final_endpoint: The model contains many possible endpoints.
|
||||
`final_endpoint` specifies the last endpoint for the model to be built
|
||||
up to. In addition to the output at `final_endpoint`, all the outputs
|
||||
at endpoints up to `final_endpoint` will also be returned, in a
|
||||
dictionary. `final_endpoint` must be one of
|
||||
InceptionI3d.VALID_ENDPOINTS (default 'Logits').
|
||||
name: A string (optional). The name of this module.
|
||||
Raises:
|
||||
ValueError: if `final_endpoint` is not recognized.
|
||||
"""
|
||||
|
||||
if final_endpoint not in self.VALID_ENDPOINTS:
|
||||
raise ValueError('Unknown final endpoint %s' % final_endpoint)
|
||||
|
||||
super(InceptionI3d, self).__init__()
|
||||
self._num_classes = num_classes
|
||||
self._spatial_squeeze = spatial_squeeze
|
||||
self._final_endpoint = final_endpoint
|
||||
self.logits = None
|
||||
|
||||
if self._final_endpoint not in self.VALID_ENDPOINTS:
|
||||
raise ValueError('Unknown final endpoint %s' % self._final_endpoint)
|
||||
|
||||
self.end_points = {}
|
||||
end_point = 'Conv3d_1a_7x7'
|
||||
self.end_points[end_point] = Unit3D(in_channels=in_channels, output_channels=64, kernel_shape=[7, 7, 7],
|
||||
stride=(2, 2, 2), padding=(3,3,3), name=name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'MaxPool3d_2a_3x3'
|
||||
self.end_points[end_point] = MaxPool3dSamePadding(kernel_size=[1, 3, 3], stride=(1, 2, 2),
|
||||
padding=0)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Conv3d_2b_1x1'
|
||||
self.end_points[end_point] = Unit3D(in_channels=64, output_channels=64, kernel_shape=[1, 1, 1], padding=0,
|
||||
name=name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Conv3d_2c_3x3'
|
||||
self.end_points[end_point] = Unit3D(in_channels=64, output_channels=192, kernel_shape=[3, 3, 3], padding=1,
|
||||
name=name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'MaxPool3d_3a_3x3'
|
||||
self.end_points[end_point] = MaxPool3dSamePadding(kernel_size=[1, 3, 3], stride=(1, 2, 2),
|
||||
padding=0)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_3b'
|
||||
self.end_points[end_point] = InceptionModule(192, [64,96,128,16,32,32], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_3c'
|
||||
self.end_points[end_point] = InceptionModule(256, [128,128,192,32,96,64], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'MaxPool3d_4a_3x3'
|
||||
self.end_points[end_point] = MaxPool3dSamePadding(kernel_size=[3, 3, 3], stride=(2, 2, 2),
|
||||
padding=0)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_4b'
|
||||
self.end_points[end_point] = InceptionModule(128+192+96+64, [192,96,208,16,48,64], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_4c'
|
||||
self.end_points[end_point] = InceptionModule(192+208+48+64, [160,112,224,24,64,64], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_4d'
|
||||
self.end_points[end_point] = InceptionModule(160+224+64+64, [128,128,256,24,64,64], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_4e'
|
||||
self.end_points[end_point] = InceptionModule(128+256+64+64, [112,144,288,32,64,64], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_4f'
|
||||
self.end_points[end_point] = InceptionModule(112+288+64+64, [256,160,320,32,128,128], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'MaxPool3d_5a_2x2'
|
||||
self.end_points[end_point] = MaxPool3dSamePadding(kernel_size=[2, 2, 2], stride=(2, 2, 2),
|
||||
padding=0)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_5b'
|
||||
self.end_points[end_point] = InceptionModule(256+320+128+128, [256,160,320,32,128,128], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_5c'
|
||||
self.end_points[end_point] = InceptionModule(256+320+128+128, [384,192,384,48,128,128], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Logits'
|
||||
self.avg_pool = nn.AvgPool3d(kernel_size=[2, 7, 7],
|
||||
stride=(1, 1, 1))
|
||||
self.dropout = nn.Dropout(dropout_keep_prob)
|
||||
self.logits = Unit3D(in_channels=384+384+128+128, output_channels=self._num_classes,
|
||||
kernel_shape=[1, 1, 1],
|
||||
padding=0,
|
||||
activation_fn=None,
|
||||
use_batch_norm=False,
|
||||
use_bias=True,
|
||||
name='logits')
|
||||
|
||||
self.build()
|
||||
|
||||
|
||||
def replace_logits(self, num_classes):
|
||||
self._num_classes = num_classes
|
||||
self.logits = Unit3D(in_channels=384+384+128+128, output_channels=self._num_classes,
|
||||
kernel_shape=[1, 1, 1],
|
||||
padding=0,
|
||||
activation_fn=None,
|
||||
use_batch_norm=False,
|
||||
use_bias=True,
|
||||
name='logits')
|
||||
|
||||
|
||||
def build(self):
|
||||
for k in self.end_points.keys():
|
||||
self.add_module(k, self.end_points[k])
|
||||
|
||||
def forward(self, x):
|
||||
for end_point in self.VALID_ENDPOINTS:
|
||||
if end_point in self.end_points:
|
||||
x = self._modules[end_point](x) # use _modules to work with dataparallel
|
||||
|
||||
x = self.logits(self.dropout(self.avg_pool(x)))
|
||||
if self._spatial_squeeze:
|
||||
logits = x.squeeze(3).squeeze(3)
|
||||
logits = logits.mean(dim=2)
|
||||
# logits is batch X time X classes, which is what we want to work with
|
||||
return logits
|
||||
|
||||
|
||||
def extract_features(self, x):
|
||||
for end_point in self.VALID_ENDPOINTS:
|
||||
if end_point in self.end_points:
|
||||
x = self._modules[end_point](x)
|
||||
return self.avg_pool(x)
|
||||
@@ -0,0 +1,23 @@
|
||||
# clip_score cross modality
|
||||
python eval_clip_score.py \
|
||||
--real_path path/to/image \
|
||||
--generated_path path/to/text \
|
||||
--batch-size 50 \
|
||||
--device "cuda"
|
||||
|
||||
# clip_score within the same modality
|
||||
python eval_clip_score.py \
|
||||
--real_path path/to/textA \
|
||||
--generated_path path/to/textB \
|
||||
--real_flag txt \
|
||||
--generated_flag txt \
|
||||
--batch-size 50 \
|
||||
--device "cuda"
|
||||
|
||||
python eval_clip_score.py \
|
||||
--real_path path/to/imageA \
|
||||
--generated_path path/to/imageB \
|
||||
--real_flag img \
|
||||
--generated_flag img \
|
||||
--batch-size 50 \
|
||||
--device "cuda"
|
||||
@@ -0,0 +1,9 @@
|
||||
python eval_common_metric.py \
|
||||
--real_video_dir path/to/imageA\
|
||||
--generated_video_dir path/to/imageB \
|
||||
--batch_size 10 \
|
||||
--crop_size 64 \
|
||||
--num_frames 20 \
|
||||
--device 'cuda' \
|
||||
--metric 'fvd' \
|
||||
--fvd_method 'styleganv'
|
||||
@@ -0,0 +1,8 @@
|
||||
python eval_common_metric.py \
|
||||
--real_video_dir path/to/imageA\
|
||||
--generated_video_dir path/to/imageB \
|
||||
--batch_size 10 \
|
||||
--num_frames 20 \
|
||||
--crop_size 64 \
|
||||
--device 'cuda' \
|
||||
--metric 'lpips'
|
||||
@@ -0,0 +1,9 @@
|
||||
|
||||
python eval_common_metric.py \
|
||||
--real_video_dir /data/xiaogeng_liu/data/video1 \
|
||||
--generated_video_dir /data/xiaogeng_liu/data/video2 \
|
||||
--batch_size 10 \
|
||||
--num_frames 20 \
|
||||
--crop_size 64 \
|
||||
--device 'cuda' \
|
||||
--metric 'psnr'
|
||||
@@ -0,0 +1,8 @@
|
||||
python eval_common_metric.py \
|
||||
--real_video_dir /data/xiaogeng_liu/data/video1 \
|
||||
--generated_video_dir /data/xiaogeng_liu/data/video2 \
|
||||
--batch_size 10 \
|
||||
--num_frames 20 \
|
||||
--crop_size 64 \
|
||||
--device 'cuda' \
|
||||
--metric 'ssim'
|
||||
@@ -0,0 +1 @@
|
||||
from .causalvideovae.model import CausalVAEModelWrapper
|
||||
@@ -0,0 +1,32 @@
|
||||
from torchvision.transforms import Lambda
|
||||
from .model.causal_vae import CausalVAEModelWrapper
|
||||
|
||||
ae_stride_config = {
|
||||
'CausalVAEModel_D4_2x8x8': [2, 8, 8],
|
||||
'CausalVAEModel_D8_2x8x8': [2, 8, 8],
|
||||
'CausalVAEModel_D4_4x8x8': [4, 8, 8],
|
||||
'CausalVAEModel_D8_4x8x8': [4, 8, 8],
|
||||
}
|
||||
|
||||
|
||||
ae_channel_config = {
|
||||
'CausalVAEModel_D4_2x8x8': 4,
|
||||
'CausalVAEModel_D8_2x8x8': 8,
|
||||
'CausalVAEModel_D4_4x8x8': 4,
|
||||
'CausalVAEModel_D8_4x8x8': 8,
|
||||
}
|
||||
|
||||
|
||||
ae_denorm = {
|
||||
'CausalVAEModel_D4_2x8x8': lambda x: (x + 1.) / 2.,
|
||||
'CausalVAEModel_D8_2x8x8': lambda x: (x + 1.) / 2.,
|
||||
'CausalVAEModel_D4_4x8x8': lambda x: (x + 1.) / 2.,
|
||||
'CausalVAEModel_D8_4x8x8': lambda x: (x + 1.) / 2.,
|
||||
}
|
||||
|
||||
ae_norm = {
|
||||
'CausalVAEModel_D4_2x8x8': Lambda(lambda x: 2. * x - 1.),
|
||||
'CausalVAEModel_D8_2x8x8': Lambda(lambda x: 2. * x - 1.),
|
||||
'CausalVAEModel_D4_4x8x8': Lambda(lambda x: 2. * x - 1.),
|
||||
'CausalVAEModel_D8_4x8x8': Lambda(lambda x: 2. * x - 1.),
|
||||
}
|
||||
+65
@@ -0,0 +1,65 @@
|
||||
from torchvision.transforms import Compose
|
||||
from transformers import AutoTokenizer
|
||||
|
||||
from .feature_datasets import T2V_Feature_dataset, T2V_T5_Feature_dataset
|
||||
from torchvision import transforms
|
||||
from torchvision.transforms import Lambda
|
||||
|
||||
from .t2v_datasets import T2V_dataset
|
||||
from .transform import ToTensorVideo, TemporalRandomCrop, RandomHorizontalFlipVideo, CenterCropResizeVideo, LongSideResizeVideo, SpatialStrideCropVideo
|
||||
|
||||
|
||||
ae_norm = {
|
||||
'CausalVAEModel_4x8x8': Lambda(lambda x: 2. * x - 1.),
|
||||
'CausalVQVAEModel_4x4x4': Lambda(lambda x: x - 0.5),
|
||||
'CausalVQVAEModel_4x8x8': Lambda(lambda x: x - 0.5),
|
||||
'VQVAEModel_4x4x4': Lambda(lambda x: x - 0.5),
|
||||
'VQVAEModel_4x8x8': Lambda(lambda x: x - 0.5),
|
||||
"bair_stride4x2x2": Lambda(lambda x: x - 0.5),
|
||||
"ucf101_stride4x4x4": Lambda(lambda x: x - 0.5),
|
||||
"kinetics_stride4x4x4": Lambda(lambda x: x - 0.5),
|
||||
"kinetics_stride2x4x4": Lambda(lambda x: x - 0.5),
|
||||
'stabilityai/sd-vae-ft-mse': transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
|
||||
'stabilityai/sd-vae-ft-ema': transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
|
||||
'vqgan_imagenet_f16_1024': Lambda(lambda x: 2. * x - 1.),
|
||||
'vqgan_imagenet_f16_16384': Lambda(lambda x: 2. * x - 1.),
|
||||
'vqgan_gumbel_f8': Lambda(lambda x: 2. * x - 1.),
|
||||
|
||||
}
|
||||
ae_denorm = {
|
||||
'CausalVAEModel_4x8x8': lambda x: (x + 1.) / 2.,
|
||||
'CausalVQVAEModel_4x4x4': lambda x: x + 0.5,
|
||||
'CausalVQVAEModel_4x8x8': lambda x: x + 0.5,
|
||||
'VQVAEModel_4x4x4': lambda x: x + 0.5,
|
||||
'VQVAEModel_4x8x8': lambda x: x + 0.5,
|
||||
"bair_stride4x2x2": lambda x: x + 0.5,
|
||||
"ucf101_stride4x4x4": lambda x: x + 0.5,
|
||||
"kinetics_stride4x4x4": lambda x: x + 0.5,
|
||||
"kinetics_stride2x4x4": lambda x: x + 0.5,
|
||||
'stabilityai/sd-vae-ft-mse': lambda x: 0.5 * x + 0.5,
|
||||
'stabilityai/sd-vae-ft-ema': lambda x: 0.5 * x + 0.5,
|
||||
'vqgan_imagenet_f16_1024': lambda x: (x + 1.) / 2.,
|
||||
'vqgan_imagenet_f16_16384': lambda x: (x + 1.) / 2.,
|
||||
'vqgan_gumbel_f8': lambda x: (x + 1.) / 2.,
|
||||
}
|
||||
|
||||
def getdataset(args):
|
||||
temporal_sample = TemporalRandomCrop(args.num_frames * args.sample_rate) # 16 x
|
||||
norm_fun = ae_norm[args.ae]
|
||||
if args.dataset == 't2v':
|
||||
if args.multi_scale:
|
||||
resize = [
|
||||
LongSideResizeVideo(args.max_image_size, skip_low_resolution=True),
|
||||
SpatialStrideCropVideo(args.stride)
|
||||
]
|
||||
else:
|
||||
resize = [CenterCropResizeVideo(args.max_image_size), ]
|
||||
transform = transforms.Compose([
|
||||
ToTensorVideo(),
|
||||
*resize,
|
||||
# RandomHorizontalFlipVideo(p=0.5), # in case their caption have position decription
|
||||
norm_fun
|
||||
])
|
||||
tokenizer = AutoTokenizer.from_pretrained(args.text_encoder_name, cache_dir=args.cache_dir)
|
||||
return T2V_dataset(args, transform=transform, temporal_sample=temporal_sample, tokenizer=tokenizer)
|
||||
raise NotImplementedError(args.dataset)
|
||||
+213
@@ -0,0 +1,213 @@
|
||||
import json
|
||||
import os
|
||||
import torch
|
||||
import random
|
||||
import torch.utils.data as data
|
||||
|
||||
import numpy as np
|
||||
from glob import glob
|
||||
from PIL import Image
|
||||
from torch.utils.data import Dataset
|
||||
from tqdm import tqdm
|
||||
|
||||
from .transform import center_crop, RandomCropVideo
|
||||
from ..utils.dataset_utils import DecordInit
|
||||
|
||||
|
||||
class T2V_Feature_dataset(Dataset):
|
||||
def __init__(self, args, temporal_sample):
|
||||
|
||||
self.video_folder = args.video_folder
|
||||
self.num_frames = args.video_length
|
||||
self.temporal_sample = temporal_sample
|
||||
|
||||
print('Building dataset...')
|
||||
if os.path.exists('samples_430k.json'):
|
||||
with open('samples_430k.json', 'r') as f:
|
||||
self.samples = json.load(f)
|
||||
else:
|
||||
self.samples = self._make_dataset()
|
||||
with open('samples_430k.json', 'w') as f:
|
||||
json.dump(self.samples, f, indent=2)
|
||||
|
||||
self.use_image_num = args.use_image_num
|
||||
self.use_img_from_vid = args.use_img_from_vid
|
||||
if self.use_image_num != 0 and not self.use_img_from_vid:
|
||||
self.img_cap_list = self.get_img_cap_list()
|
||||
|
||||
def _make_dataset(self):
|
||||
all_mp4 = list(glob(os.path.join(self.video_folder, '**', '*.mp4'), recursive=True))
|
||||
# all_mp4 = all_mp4[:1000]
|
||||
samples = []
|
||||
for i in tqdm(all_mp4):
|
||||
video_id = os.path.basename(i).split('.')[0]
|
||||
ae = os.path.split(i)[0].replace('data_split_tt', 'lb_causalvideovae444_feature')
|
||||
ae = os.path.join(ae, f'{video_id}_causalvideovae444.npy')
|
||||
if not os.path.exists(ae):
|
||||
continue
|
||||
|
||||
t5 = os.path.split(i)[0].replace('data_split_tt', 'lb_t5_feature')
|
||||
cond_list = []
|
||||
cond_llava = os.path.join(t5, f'{video_id}_t5_llava_fea.npy')
|
||||
mask_llava = os.path.join(t5, f'{video_id}_t5_llava_mask.npy')
|
||||
if os.path.exists(cond_llava) and os.path.exists(mask_llava):
|
||||
llava = dict(cond=cond_llava, mask=mask_llava)
|
||||
cond_list.append(llava)
|
||||
cond_sharegpt4v = os.path.join(t5, f'{video_id}_t5_sharegpt4v_fea.npy')
|
||||
mask_sharegpt4v = os.path.join(t5, f'{video_id}_t5_sharegpt4v_mask.npy')
|
||||
if os.path.exists(cond_sharegpt4v) and os.path.exists(mask_sharegpt4v):
|
||||
sharegpt4v = dict(cond=cond_sharegpt4v, mask=mask_sharegpt4v)
|
||||
cond_list.append(sharegpt4v)
|
||||
if len(cond_list) > 0:
|
||||
sample = dict(ae=ae, t5=cond_list)
|
||||
samples.append(sample)
|
||||
return samples
|
||||
|
||||
def __len__(self):
|
||||
return len(self.samples)
|
||||
|
||||
def __getitem__(self, idx):
|
||||
# try:
|
||||
sample = self.samples[idx]
|
||||
ae, t5 = sample['ae'], sample['t5']
|
||||
t5 = random.choice(t5)
|
||||
video_origin = np.load(ae)[0] # C T H W
|
||||
_, total_frames, _, _ = video_origin.shape
|
||||
# Sampling video frames
|
||||
start_frame_ind, end_frame_ind = self.temporal_sample(total_frames)
|
||||
assert end_frame_ind - start_frame_ind >= self.num_frames
|
||||
select_video_idx = np.linspace(start_frame_ind, end_frame_ind - 1, num=self.num_frames, dtype=int) # start, stop, num=50
|
||||
# print('select_video_idx', total_frames, select_video_idx)
|
||||
video = video_origin[:, select_video_idx] # C num_frames H W
|
||||
video = torch.from_numpy(video)
|
||||
|
||||
cond = torch.from_numpy(np.load(t5['cond']))[0] # L
|
||||
cond_mask = torch.from_numpy(np.load(t5['mask']))[0] # L D
|
||||
|
||||
if self.use_image_num != 0 and self.use_img_from_vid:
|
||||
select_image_idx = np.random.randint(0, total_frames, self.use_image_num)
|
||||
# print('select_image_idx', total_frames, self.use_image_num, select_image_idx)
|
||||
images = video_origin[:, select_image_idx] # c, num_img, h, w
|
||||
images = torch.from_numpy(images)
|
||||
video = torch.cat([video, images], dim=1) # c, num_frame+num_img, h, w
|
||||
cond = torch.stack([cond] * (1+self.use_image_num)) # 1+self.use_image_num, l
|
||||
cond_mask = torch.stack([cond_mask] * (1+self.use_image_num)) # 1+self.use_image_num, l
|
||||
elif self.use_image_num != 0 and not self.use_img_from_vid:
|
||||
images, captions = self.img_cap_list[idx]
|
||||
raise NotImplementedError
|
||||
else:
|
||||
pass
|
||||
|
||||
return video, cond, cond_mask
|
||||
# except Exception as e:
|
||||
# print(f'Error with {e}, {sample}')
|
||||
# return self.__getitem__(random.randint(0, self.__len__() - 1))
|
||||
|
||||
def get_img_cap_list(self):
|
||||
raise NotImplementedError
|
||||
|
||||
|
||||
|
||||
|
||||
class T2V_T5_Feature_dataset(Dataset):
|
||||
def __init__(self, args, transform, temporal_sample):
|
||||
|
||||
self.video_folder = args.video_folder
|
||||
self.num_frames = args.num_frames
|
||||
self.transform = transform
|
||||
self.temporal_sample = temporal_sample
|
||||
self.v_decoder = DecordInit()
|
||||
|
||||
print('Building dataset...')
|
||||
if os.path.exists('samples_430k.json'):
|
||||
with open('samples_430k.json', 'r') as f:
|
||||
self.samples = json.load(f)
|
||||
self.samples = [dict(ae=i['ae'].replace('lb_causalvideovae444_feature', 'data_split_1024').replace('_causalvideovae444.npy', '.mp4'), t5=i['t5']) for i in self.samples]
|
||||
else:
|
||||
self.samples = self._make_dataset()
|
||||
with open('samples_430k.json', 'w') as f:
|
||||
json.dump(self.samples, f, indent=2)
|
||||
|
||||
self.use_image_num = args.use_image_num
|
||||
self.use_img_from_vid = args.use_img_from_vid
|
||||
if self.use_image_num != 0 and not self.use_img_from_vid:
|
||||
self.img_cap_list = self.get_img_cap_list()
|
||||
|
||||
def _make_dataset(self):
|
||||
all_mp4 = list(glob(os.path.join(self.video_folder, '**', '*.mp4'), recursive=True))
|
||||
# all_mp4 = all_mp4[:1000]
|
||||
samples = []
|
||||
for i in tqdm(all_mp4):
|
||||
video_id = os.path.basename(i).split('.')[0]
|
||||
# ae = os.path.split(i)[0].replace('data_split', 'lb_causalvideovae444_feature')
|
||||
# ae = os.path.join(ae, f'{video_id}_causalvideovae444.npy')
|
||||
ae = i
|
||||
if not os.path.exists(ae):
|
||||
continue
|
||||
|
||||
t5 = os.path.split(i)[0].replace('data_split_1024', 'lb_t5_feature')
|
||||
cond_list = []
|
||||
cond_llava = os.path.join(t5, f'{video_id}_t5_llava_fea.npy')
|
||||
mask_llava = os.path.join(t5, f'{video_id}_t5_llava_mask.npy')
|
||||
if os.path.exists(cond_llava) and os.path.exists(mask_llava):
|
||||
llava = dict(cond=cond_llava, mask=mask_llava)
|
||||
cond_list.append(llava)
|
||||
cond_sharegpt4v = os.path.join(t5, f'{video_id}_t5_sharegpt4v_fea.npy')
|
||||
mask_sharegpt4v = os.path.join(t5, f'{video_id}_t5_sharegpt4v_mask.npy')
|
||||
if os.path.exists(cond_sharegpt4v) and os.path.exists(mask_sharegpt4v):
|
||||
sharegpt4v = dict(cond=cond_sharegpt4v, mask=mask_sharegpt4v)
|
||||
cond_list.append(sharegpt4v)
|
||||
if len(cond_list) > 0:
|
||||
sample = dict(ae=ae, t5=cond_list)
|
||||
samples.append(sample)
|
||||
return samples
|
||||
|
||||
def __len__(self):
|
||||
return len(self.samples)
|
||||
|
||||
def __getitem__(self, idx):
|
||||
try:
|
||||
sample = self.samples[idx]
|
||||
ae, t5 = sample['ae'], sample['t5']
|
||||
t5 = random.choice(t5)
|
||||
|
||||
video = self.decord_read(ae)
|
||||
video = self.transform(video) # T C H W -> T C H W
|
||||
video = video.transpose(0, 1) # T C H W -> C T H W
|
||||
total_frames = video.shape[1]
|
||||
cond = torch.from_numpy(np.load(t5['cond']))[0] # L
|
||||
cond_mask = torch.from_numpy(np.load(t5['mask']))[0] # L D
|
||||
|
||||
if self.use_image_num != 0 and self.use_img_from_vid:
|
||||
select_image_idx = np.random.randint(0, total_frames, self.use_image_num)
|
||||
# print('select_image_idx', total_frames, self.use_image_num, select_image_idx)
|
||||
images = video.numpy()[:, select_image_idx] # c, num_img, h, w
|
||||
images = torch.from_numpy(images)
|
||||
video = torch.cat([video, images], dim=1) # c, num_frame+num_img, h, w
|
||||
cond = torch.stack([cond] * (1+self.use_image_num)) # 1+self.use_image_num, l
|
||||
cond_mask = torch.stack([cond_mask] * (1+self.use_image_num)) # 1+self.use_image_num, l
|
||||
elif self.use_image_num != 0 and not self.use_img_from_vid:
|
||||
images, captions = self.img_cap_list[idx]
|
||||
raise NotImplementedError
|
||||
else:
|
||||
pass
|
||||
|
||||
return video, cond, cond_mask
|
||||
except Exception as e:
|
||||
print(f'Error with {e}, {sample}')
|
||||
return self.__getitem__(random.randint(0, self.__len__() - 1))
|
||||
|
||||
def decord_read(self, path):
|
||||
decord_vr = self.v_decoder(path)
|
||||
total_frames = len(decord_vr)
|
||||
# Sampling video frames
|
||||
start_frame_ind, end_frame_ind = self.temporal_sample(total_frames)
|
||||
# assert end_frame_ind - start_frame_ind >= self.num_frames
|
||||
frame_indice = np.linspace(start_frame_ind, end_frame_ind - 1, self.num_frames, dtype=int)
|
||||
video_data = decord_vr.get_batch(frame_indice).asnumpy()
|
||||
video_data = torch.from_numpy(video_data)
|
||||
video_data = video_data.permute(0, 3, 1, 2) # (T, H, W, C) -> (T C H W)
|
||||
return video_data
|
||||
|
||||
def get_img_cap_list(self):
|
||||
raise NotImplementedError
|
||||
+203
@@ -0,0 +1,203 @@
|
||||
import json
|
||||
import os, io, csv, math, random
|
||||
import numpy as np
|
||||
import torchvision
|
||||
from einops import rearrange
|
||||
from decord import VideoReader
|
||||
from os.path import join as opj
|
||||
import gc
|
||||
import torch
|
||||
import torchvision.transforms as transforms
|
||||
from torch.utils.data.dataset import Dataset
|
||||
from tqdm import tqdm
|
||||
from PIL import Image
|
||||
|
||||
from ..utils.dataset_utils import DecordInit
|
||||
from ..utils.utils import text_preprocessing
|
||||
|
||||
|
||||
def random_video_noise(t, c, h, w):
|
||||
vid = torch.rand(t, c, h, w) * 255.0
|
||||
vid = vid.to(torch.uint8)
|
||||
return vid
|
||||
|
||||
class T2V_dataset(Dataset):
|
||||
def __init__(self, args, transform, temporal_sample, tokenizer):
|
||||
self.image_data = args.image_data
|
||||
self.video_data = args.video_data
|
||||
self.num_frames = args.num_frames
|
||||
self.transform = transform
|
||||
self.temporal_sample = temporal_sample
|
||||
self.tokenizer = tokenizer
|
||||
self.model_max_length = args.model_max_length
|
||||
self.v_decoder = DecordInit()
|
||||
|
||||
self.vid_cap_list = self.get_vid_cap_list()
|
||||
|
||||
self.use_image_num = args.use_image_num
|
||||
self.use_img_from_vid = args.use_img_from_vid
|
||||
if self.use_image_num != 0 and not self.use_img_from_vid:
|
||||
self.img_cap_list = self.get_img_cap_list()
|
||||
|
||||
|
||||
def __len__(self):
|
||||
return len(self.vid_cap_list)
|
||||
|
||||
def __getitem__(self, idx):
|
||||
try:
|
||||
# import ipdb;ipdb.set_trace()
|
||||
video_data = self.get_video(idx)
|
||||
image_data = {}
|
||||
if self.use_image_num != 0 and self.use_img_from_vid:
|
||||
image_data = self.get_image_from_video(video_data)
|
||||
elif self.use_image_num != 0 and not self.use_img_from_vid:
|
||||
image_data = self.get_image(idx)
|
||||
else:
|
||||
raise NotImplementedError
|
||||
gc.collect()
|
||||
return dict(video_data=video_data, image_data=image_data)
|
||||
except Exception as e:
|
||||
# print(f'Error with {e}, {self.vid_cap_list[idx]}')
|
||||
if os.path.exists(self.vid_cap_list[idx]['path']) and '_resize_1080p' in self.vid_cap_list[idx]['path']:
|
||||
os.remove(self.vid_cap_list[idx]['path'])
|
||||
print('remove:', self.vid_cap_list[idx]['path'])
|
||||
return self.__getitem__(random.randint(0, self.__len__() - 1))
|
||||
|
||||
def get_video(self, idx):
|
||||
# video = random.choice([random_video_noise(65, 3, 720, 360) * 255, random_video_noise(65, 3, 1024, 1024), random_video_noise(65, 3, 360, 720)])
|
||||
# # print('random shape', video.shape)
|
||||
# input_ids = torch.ones(1, 120).to(torch.long).squeeze(0)
|
||||
# cond_mask = torch.cat([torch.ones(1, 60).to(torch.long), torch.ones(1, 60).to(torch.long)], dim=1).squeeze(0)
|
||||
|
||||
video_path = self.vid_cap_list[idx]['path']
|
||||
frame_idx = self.vid_cap_list[idx]['frame_idx']
|
||||
#print('before decord')
|
||||
video = self.decord_read(video_path, frame_idx)
|
||||
# video = self.tv_read(video_path, frame_idx)
|
||||
#print('after decord')
|
||||
video = self.transform(video) # T C H W -> T C H W
|
||||
# del raw_video
|
||||
# gc.collect()
|
||||
# video = torch.rand(65, 3, 512, 512)
|
||||
#print('after transform')
|
||||
video = video.transpose(0, 1) # T C H W -> C T H W
|
||||
text = self.vid_cap_list[idx]['cap']
|
||||
|
||||
text = text_preprocessing(text)
|
||||
text_tokens_and_mask = self.tokenizer(
|
||||
text,
|
||||
max_length=self.model_max_length,
|
||||
padding='max_length',
|
||||
truncation=True,
|
||||
return_attention_mask=True,
|
||||
add_special_tokens=True,
|
||||
return_tensors='pt'
|
||||
)
|
||||
input_ids = text_tokens_and_mask['input_ids']
|
||||
cond_mask = text_tokens_and_mask['attention_mask']
|
||||
return dict(video=video, input_ids=input_ids, cond_mask=cond_mask)
|
||||
|
||||
def get_image_from_video(self, video_data):
|
||||
select_image_idx = np.linspace(0, self.num_frames-1, self.use_image_num, dtype=int)
|
||||
assert self.num_frames >= self.use_image_num
|
||||
image = [video_data['video'][:, i:i+1] for i in select_image_idx] # num_img [c, 1, h, w]
|
||||
input_ids = video_data['input_ids'].repeat(self.use_image_num, 1) # self.use_image_num, l
|
||||
cond_mask = video_data['cond_mask'].repeat(self.use_image_num, 1) # self.use_image_num, l
|
||||
return dict(image=image, input_ids=input_ids, cond_mask=cond_mask)
|
||||
|
||||
def get_image(self, idx):
|
||||
idx = idx % len(self.img_cap_list) # out of range
|
||||
image_data = self.img_cap_list[idx] # [{'path': path, 'cap': cap}, ...]
|
||||
|
||||
image = [Image.open(i['path']).convert('RGB') for i in image_data] # num_img [h, w, c]
|
||||
image = [torch.from_numpy(np.array(i)) for i in image] # num_img [h, w, c]
|
||||
image = [rearrange(i, 'h w c -> c h w').unsqueeze(0) for i in image] # num_img [1 c h w]
|
||||
image = [self.transform(i) for i in image] # num_img [1 C H W] -> num_img [1 C H W]
|
||||
image = [i.transpose(0, 1) for i in image] # num_img [1 C H W] -> num_img [C 1 H W]
|
||||
|
||||
caps = [i['cap'] for i in image_data]
|
||||
text = [text_preprocessing(cap) for cap in caps]
|
||||
input_ids, cond_mask = [], []
|
||||
for t in text:
|
||||
text_tokens_and_mask = self.tokenizer(
|
||||
t,
|
||||
max_length=self.model_max_length,
|
||||
padding='max_length',
|
||||
truncation=True,
|
||||
return_attention_mask=True,
|
||||
add_special_tokens=True,
|
||||
return_tensors='pt'
|
||||
)
|
||||
input_ids.append(text_tokens_and_mask['input_ids'])
|
||||
cond_mask.append(text_tokens_and_mask['attention_mask'])
|
||||
input_ids = torch.cat(input_ids) # self.use_image_num, l
|
||||
cond_mask = torch.cat(cond_mask) # self.use_image_num, l
|
||||
return dict(image=image, input_ids=input_ids, cond_mask=cond_mask)
|
||||
|
||||
def tv_read(self, path, frame_idx=None):
|
||||
vframes, aframes, info = torchvision.io.read_video(filename=path, pts_unit='sec', output_format='TCHW')
|
||||
total_frames = len(vframes)
|
||||
if frame_idx is None:
|
||||
start_frame_ind, end_frame_ind = self.temporal_sample(total_frames)
|
||||
else:
|
||||
start_frame_ind, end_frame_ind = frame_idx.split(':')
|
||||
start_frame_ind, end_frame_ind = int(start_frame_ind), int(end_frame_ind)
|
||||
# assert end_frame_ind - start_frame_ind >= self.num_frames
|
||||
frame_indice = np.linspace(start_frame_ind, end_frame_ind - 1, self.num_frames, dtype=int)
|
||||
# frame_indice = np.linspace(0, 63, self.num_frames, dtype=int)
|
||||
|
||||
video = vframes[frame_indice] # (T, C, H, W)
|
||||
|
||||
return video
|
||||
|
||||
def decord_read(self, path, frame_idx=None):
|
||||
decord_vr = self.v_decoder(path)
|
||||
total_frames = len(decord_vr)
|
||||
# Sampling video frames
|
||||
if frame_idx is None:
|
||||
start_frame_ind, end_frame_ind = self.temporal_sample(total_frames)
|
||||
else:
|
||||
start_frame_ind, end_frame_ind = frame_idx.split(':')
|
||||
start_frame_ind, end_frame_ind = int(start_frame_ind), int(end_frame_ind)
|
||||
start_frame_ind, end_frame_ind = int(start_frame_ind), int(start_frame_ind) + self.num_frames
|
||||
# assert end_frame_ind - start_frame_ind >= self.num_frames
|
||||
frame_indice = np.linspace(start_frame_ind, end_frame_ind - 1, self.num_frames, dtype=int)
|
||||
# frame_indice = np.linspace(0, 63, self.num_frames, dtype=int)
|
||||
|
||||
video_data = decord_vr.get_batch(frame_indice).asnumpy()
|
||||
video_data = torch.from_numpy(video_data)
|
||||
video_data = video_data.permute(0, 3, 1, 2) # (T, H, W, C) -> (T C H W)
|
||||
return video_data
|
||||
|
||||
|
||||
def get_vid_cap_list(self):
|
||||
vid_cap_lists = []
|
||||
with open(self.video_data, 'r') as f:
|
||||
folder_anno = [i.strip().split(',') for i in f.readlines() if len(i.strip()) > 0]
|
||||
# print(folder_anno)
|
||||
for folder, anno in folder_anno:
|
||||
with open(anno, 'r') as f:
|
||||
vid_cap_list = json.load(f)
|
||||
print(f'Building {anno}...')
|
||||
for i in tqdm(range(len(vid_cap_list))):
|
||||
path = opj(folder, vid_cap_list[i]['path'])
|
||||
if os.path.exists(path.replace('.mp4', '_resize_1080p.mp4')):
|
||||
path = path.replace('.mp4', '_resize_1080p.mp4')
|
||||
vid_cap_list[i]['path'] = path
|
||||
|
||||
vid_cap_lists += vid_cap_list
|
||||
return vid_cap_lists
|
||||
|
||||
def get_img_cap_list(self):
|
||||
img_cap_lists = []
|
||||
with open(self.image_data, 'r') as f:
|
||||
folder_anno = [i.strip().split(',') for i in f.readlines() if len(i.strip()) > 0]
|
||||
for folder, anno in folder_anno:
|
||||
with open(anno, 'r') as f:
|
||||
img_cap_list = json.load(f)
|
||||
print(f'Building {anno}...')
|
||||
for i in tqdm(range(len(img_cap_list))):
|
||||
img_cap_list[i]['path'] = opj(folder, img_cap_list[i]['path'])
|
||||
img_cap_lists += img_cap_list
|
||||
img_cap_lists = [img_cap_lists[i: i+self.use_image_num] for i in range(0, len(img_cap_lists), self.use_image_num)]
|
||||
return img_cap_lists[:-1] # drop last to avoid error length
|
||||
+573
@@ -0,0 +1,573 @@
|
||||
import torch
|
||||
import random
|
||||
import numbers
|
||||
from torchvision.transforms import RandomCrop, RandomResizedCrop
|
||||
|
||||
|
||||
def _is_tensor_video_clip(clip):
|
||||
if not torch.is_tensor(clip):
|
||||
raise TypeError("clip should be Tensor. Got %s" % type(clip))
|
||||
|
||||
if not clip.ndimension() == 4:
|
||||
raise ValueError("clip should be 4D. Got %dD" % clip.dim())
|
||||
|
||||
return True
|
||||
|
||||
|
||||
def center_crop_arr(pil_image, image_size):
|
||||
"""
|
||||
Center cropping implementation from ADM.
|
||||
https://github.com/openai/guided-diffusion/blob/8fb3ad9197f16bbc40620447b2742e13458d2831/guided_diffusion/image_datasets.py#L126
|
||||
"""
|
||||
while min(*pil_image.size) >= 2 * image_size:
|
||||
pil_image = pil_image.resize(
|
||||
tuple(x // 2 for x in pil_image.size), resample=Image.BOX
|
||||
)
|
||||
|
||||
scale = image_size / min(*pil_image.size)
|
||||
pil_image = pil_image.resize(
|
||||
tuple(round(x * scale) for x in pil_image.size), resample=Image.BICUBIC
|
||||
)
|
||||
|
||||
arr = np.array(pil_image)
|
||||
crop_y = (arr.shape[0] - image_size) // 2
|
||||
crop_x = (arr.shape[1] - image_size) // 2
|
||||
return Image.fromarray(arr[crop_y: crop_y + image_size, crop_x: crop_x + image_size])
|
||||
|
||||
|
||||
def crop(clip, i, j, h, w):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
"""
|
||||
if len(clip.size()) != 4:
|
||||
raise ValueError("clip should be a 4D tensor")
|
||||
return clip[..., i: i + h, j: j + w]
|
||||
|
||||
|
||||
def resize(clip, target_size, interpolation_mode):
|
||||
if len(target_size) != 2:
|
||||
raise ValueError(f"target size should be tuple (height, width), instead got {target_size}")
|
||||
return torch.nn.functional.interpolate(clip, size=target_size, mode=interpolation_mode, align_corners=True, antialias=True)
|
||||
|
||||
|
||||
def resize_scale(clip, target_size, interpolation_mode):
|
||||
if len(target_size) != 2:
|
||||
raise ValueError(f"target size should be tuple (height, width), instead got {target_size}")
|
||||
H, W = clip.size(-2), clip.size(-1)
|
||||
scale_ = target_size[0] / min(H, W)
|
||||
return torch.nn.functional.interpolate(clip, scale_factor=scale_, mode=interpolation_mode, align_corners=True, antialias=True)
|
||||
|
||||
|
||||
def resized_crop(clip, i, j, h, w, size, interpolation_mode="bilinear"):
|
||||
"""
|
||||
Do spatial cropping and resizing to the video clip
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
i (int): i in (i,j) i.e coordinates of the upper left corner.
|
||||
j (int): j in (i,j) i.e coordinates of the upper left corner.
|
||||
h (int): Height of the cropped region.
|
||||
w (int): Width of the cropped region.
|
||||
size (tuple(int, int)): height and width of resized clip
|
||||
Returns:
|
||||
clip (torch.tensor): Resized and cropped clip. Size is (T, C, H, W)
|
||||
"""
|
||||
if not _is_tensor_video_clip(clip):
|
||||
raise ValueError("clip should be a 4D torch.tensor")
|
||||
clip = crop(clip, i, j, h, w)
|
||||
clip = resize(clip, size, interpolation_mode)
|
||||
return clip
|
||||
|
||||
|
||||
def center_crop(clip, crop_size):
|
||||
if not _is_tensor_video_clip(clip):
|
||||
raise ValueError("clip should be a 4D torch.tensor")
|
||||
h, w = clip.size(-2), clip.size(-1)
|
||||
th, tw = crop_size
|
||||
if h < th or w < tw:
|
||||
raise ValueError("height and width must be no smaller than crop_size")
|
||||
|
||||
i = int(round((h - th) / 2.0))
|
||||
j = int(round((w - tw) / 2.0))
|
||||
return crop(clip, i, j, th, tw)
|
||||
|
||||
|
||||
def center_crop_using_short_edge(clip):
|
||||
if not _is_tensor_video_clip(clip):
|
||||
raise ValueError("clip should be a 4D torch.tensor")
|
||||
h, w = clip.size(-2), clip.size(-1)
|
||||
if h < w:
|
||||
th, tw = h, h
|
||||
i = 0
|
||||
j = int(round((w - tw) / 2.0))
|
||||
else:
|
||||
th, tw = w, w
|
||||
i = int(round((h - th) / 2.0))
|
||||
j = 0
|
||||
return crop(clip, i, j, th, tw)
|
||||
|
||||
|
||||
def random_shift_crop(clip):
|
||||
'''
|
||||
Slide along the long edge, with the short edge as crop size
|
||||
'''
|
||||
if not _is_tensor_video_clip(clip):
|
||||
raise ValueError("clip should be a 4D torch.tensor")
|
||||
h, w = clip.size(-2), clip.size(-1)
|
||||
|
||||
if h <= w:
|
||||
long_edge = w
|
||||
short_edge = h
|
||||
else:
|
||||
long_edge = h
|
||||
short_edge = w
|
||||
|
||||
th, tw = short_edge, short_edge
|
||||
|
||||
i = torch.randint(0, h - th + 1, size=(1,)).item()
|
||||
j = torch.randint(0, w - tw + 1, size=(1,)).item()
|
||||
return crop(clip, i, j, th, tw)
|
||||
|
||||
|
||||
def to_tensor(clip):
|
||||
"""
|
||||
Convert tensor data type from uint8 to float, divide value by 255.0 and
|
||||
permute the dimensions of clip tensor
|
||||
Args:
|
||||
clip (torch.tensor, dtype=torch.uint8): Size is (T, C, H, W)
|
||||
Return:
|
||||
clip (torch.tensor, dtype=torch.float): Size is (T, C, H, W)
|
||||
"""
|
||||
_is_tensor_video_clip(clip)
|
||||
if not clip.dtype == torch.uint8:
|
||||
raise TypeError("clip tensor should have data type uint8. Got %s" % str(clip.dtype))
|
||||
# return clip.float().permute(3, 0, 1, 2) / 255.0
|
||||
return clip.float() / 255.0
|
||||
|
||||
|
||||
def normalize(clip, mean, std, inplace=False):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be normalized. Size is (T, C, H, W)
|
||||
mean (tuple): pixel RGB mean. Size is (3)
|
||||
std (tuple): pixel standard deviation. Size is (3)
|
||||
Returns:
|
||||
normalized clip (torch.tensor): Size is (T, C, H, W)
|
||||
"""
|
||||
if not _is_tensor_video_clip(clip):
|
||||
raise ValueError("clip should be a 4D torch.tensor")
|
||||
if not inplace:
|
||||
clip = clip.clone()
|
||||
mean = torch.as_tensor(mean, dtype=clip.dtype, device=clip.device)
|
||||
# print(mean)
|
||||
std = torch.as_tensor(std, dtype=clip.dtype, device=clip.device)
|
||||
clip.sub_(mean[:, None, None, None]).div_(std[:, None, None, None])
|
||||
return clip
|
||||
|
||||
|
||||
def hflip(clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be normalized. Size is (T, C, H, W)
|
||||
Returns:
|
||||
flipped clip (torch.tensor): Size is (T, C, H, W)
|
||||
"""
|
||||
if not _is_tensor_video_clip(clip):
|
||||
raise ValueError("clip should be a 4D torch.tensor")
|
||||
return clip.flip(-1)
|
||||
|
||||
|
||||
class RandomCropVideo:
|
||||
def __init__(self, size):
|
||||
if isinstance(size, numbers.Number):
|
||||
self.size = (int(size), int(size))
|
||||
else:
|
||||
self.size = size
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
Returns:
|
||||
torch.tensor: randomly cropped video clip.
|
||||
size is (T, C, OH, OW)
|
||||
"""
|
||||
i, j, h, w = self.get_params(clip)
|
||||
return crop(clip, i, j, h, w)
|
||||
|
||||
def get_params(self, clip):
|
||||
h, w = clip.shape[-2:]
|
||||
th, tw = self.size
|
||||
|
||||
if h < th or w < tw:
|
||||
raise ValueError(f"Required crop size {(th, tw)} is larger than input image size {(h, w)}")
|
||||
|
||||
if w == tw and h == th:
|
||||
return 0, 0, h, w
|
||||
|
||||
i = torch.randint(0, h - th + 1, size=(1,)).item()
|
||||
j = torch.randint(0, w - tw + 1, size=(1,)).item()
|
||||
|
||||
return i, j, th, tw
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(size={self.size})"
|
||||
|
||||
|
||||
class SpatialStrideCropVideo:
|
||||
def __init__(self, stride):
|
||||
self.stride = stride
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
Returns:
|
||||
torch.tensor: cropped video clip by stride.
|
||||
size is (T, C, OH, OW)
|
||||
"""
|
||||
i, j, h, w = self.get_params(clip)
|
||||
return crop(clip, i, j, h, w)
|
||||
|
||||
def get_params(self, clip):
|
||||
h, w = clip.shape[-2:]
|
||||
|
||||
th, tw = h // self.stride * self.stride, w // self.stride * self.stride
|
||||
|
||||
return 0, 0, th, tw # from top-left
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(size={self.size})"
|
||||
|
||||
class LongSideResizeVideo:
|
||||
'''
|
||||
First use the long side,
|
||||
then resize to the specified size
|
||||
'''
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
size,
|
||||
skip_low_resolution=False,
|
||||
interpolation_mode="bilinear",
|
||||
):
|
||||
self.size = size
|
||||
self.skip_low_resolution = skip_low_resolution
|
||||
self.interpolation_mode = interpolation_mode
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
Returns:
|
||||
torch.tensor: scale resized video clip.
|
||||
size is (T, C, 512, *) or (T, C, *, 512)
|
||||
"""
|
||||
_, _, h, w = clip.shape
|
||||
if self.skip_low_resolution and max(h, w) <= self.size:
|
||||
return clip
|
||||
if h > w:
|
||||
w = int(w * self.size / h)
|
||||
h = self.size
|
||||
else:
|
||||
h = int(h * self.size / w)
|
||||
w = self.size
|
||||
resize_clip = resize(clip, target_size=(h, w),
|
||||
interpolation_mode=self.interpolation_mode)
|
||||
return resize_clip
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(size={self.size}, interpolation_mode={self.interpolation_mode}"
|
||||
|
||||
class CenterCropResizeVideo:
|
||||
'''
|
||||
First use the short side for cropping length,
|
||||
center crop video, then resize to the specified size
|
||||
'''
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
size,
|
||||
interpolation_mode="bilinear",
|
||||
):
|
||||
if isinstance(size, tuple):
|
||||
if len(size) != 2:
|
||||
raise ValueError(f"size should be tuple (height, width), instead got {size}")
|
||||
self.size = size
|
||||
else:
|
||||
self.size = (size, size)
|
||||
|
||||
self.interpolation_mode = interpolation_mode
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
Returns:
|
||||
torch.tensor: scale resized / center cropped video clip.
|
||||
size is (T, C, crop_size, crop_size)
|
||||
"""
|
||||
clip_center_crop = center_crop_using_short_edge(clip)
|
||||
clip_center_crop_resize = resize(clip_center_crop, target_size=self.size,
|
||||
interpolation_mode=self.interpolation_mode)
|
||||
return clip_center_crop_resize
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(size={self.size}, interpolation_mode={self.interpolation_mode}"
|
||||
|
||||
|
||||
class UCFCenterCropVideo:
|
||||
'''
|
||||
First scale to the specified size in equal proportion to the short edge,
|
||||
then center cropping
|
||||
'''
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
size,
|
||||
interpolation_mode="bilinear",
|
||||
):
|
||||
if isinstance(size, tuple):
|
||||
if len(size) != 2:
|
||||
raise ValueError(f"size should be tuple (height, width), instead got {size}")
|
||||
self.size = size
|
||||
else:
|
||||
self.size = (size, size)
|
||||
|
||||
self.interpolation_mode = interpolation_mode
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
Returns:
|
||||
torch.tensor: scale resized / center cropped video clip.
|
||||
size is (T, C, crop_size, crop_size)
|
||||
"""
|
||||
clip_resize = resize_scale(clip=clip, target_size=self.size, interpolation_mode=self.interpolation_mode)
|
||||
clip_center_crop = center_crop(clip_resize, self.size)
|
||||
return clip_center_crop
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(size={self.size}, interpolation_mode={self.interpolation_mode}"
|
||||
|
||||
|
||||
class KineticsRandomCropResizeVideo:
|
||||
'''
|
||||
Slide along the long edge, with the short edge as crop size. And resie to the desired size.
|
||||
'''
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
size,
|
||||
interpolation_mode="bilinear",
|
||||
):
|
||||
if isinstance(size, tuple):
|
||||
if len(size) != 2:
|
||||
raise ValueError(f"size should be tuple (height, width), instead got {size}")
|
||||
self.size = size
|
||||
else:
|
||||
self.size = (size, size)
|
||||
|
||||
self.interpolation_mode = interpolation_mode
|
||||
|
||||
def __call__(self, clip):
|
||||
clip_random_crop = random_shift_crop(clip)
|
||||
clip_resize = resize(clip_random_crop, self.size, self.interpolation_mode)
|
||||
return clip_resize
|
||||
|
||||
|
||||
class CenterCropVideo:
|
||||
def __init__(
|
||||
self,
|
||||
size,
|
||||
interpolation_mode="bilinear",
|
||||
):
|
||||
if isinstance(size, tuple):
|
||||
if len(size) != 2:
|
||||
raise ValueError(f"size should be tuple (height, width), instead got {size}")
|
||||
self.size = size
|
||||
else:
|
||||
self.size = (size, size)
|
||||
|
||||
self.interpolation_mode = interpolation_mode
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Video clip to be cropped. Size is (T, C, H, W)
|
||||
Returns:
|
||||
torch.tensor: center cropped video clip.
|
||||
size is (T, C, crop_size, crop_size)
|
||||
"""
|
||||
clip_center_crop = center_crop(clip, self.size)
|
||||
return clip_center_crop
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(size={self.size}, interpolation_mode={self.interpolation_mode}"
|
||||
|
||||
|
||||
class NormalizeVideo:
|
||||
"""
|
||||
Normalize the video clip by mean subtraction and division by standard deviation
|
||||
Args:
|
||||
mean (3-tuple): pixel RGB mean
|
||||
std (3-tuple): pixel RGB standard deviation
|
||||
inplace (boolean): whether do in-place normalization
|
||||
"""
|
||||
|
||||
def __init__(self, mean, std, inplace=False):
|
||||
self.mean = mean
|
||||
self.std = std
|
||||
self.inplace = inplace
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): video clip must be normalized. Size is (C, T, H, W)
|
||||
"""
|
||||
return normalize(clip, self.mean, self.std, self.inplace)
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(mean={self.mean}, std={self.std}, inplace={self.inplace})"
|
||||
|
||||
|
||||
class ToTensorVideo:
|
||||
"""
|
||||
Convert tensor data type from uint8 to float, divide value by 255.0 and
|
||||
permute the dimensions of clip tensor
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
pass
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor, dtype=torch.uint8): Size is (T, C, H, W)
|
||||
Return:
|
||||
clip (torch.tensor, dtype=torch.float): Size is (T, C, H, W)
|
||||
"""
|
||||
return to_tensor(clip)
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return self.__class__.__name__
|
||||
|
||||
|
||||
class RandomHorizontalFlipVideo:
|
||||
"""
|
||||
Flip the video clip along the horizontal direction with a given probability
|
||||
Args:
|
||||
p (float): probability of the clip being flipped. Default value is 0.5
|
||||
"""
|
||||
|
||||
def __init__(self, p=0.5):
|
||||
self.p = p
|
||||
|
||||
def __call__(self, clip):
|
||||
"""
|
||||
Args:
|
||||
clip (torch.tensor): Size is (T, C, H, W)
|
||||
Return:
|
||||
clip (torch.tensor): Size is (T, C, H, W)
|
||||
"""
|
||||
if random.random() < self.p:
|
||||
clip = hflip(clip)
|
||||
return clip
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f"{self.__class__.__name__}(p={self.p})"
|
||||
|
||||
|
||||
# ------------------------------------------------------------
|
||||
# --------------------- Sampling ---------------------------
|
||||
# ------------------------------------------------------------
|
||||
class TemporalRandomCrop(object):
|
||||
"""Temporally crop the given frame indices at a random location.
|
||||
|
||||
Args:
|
||||
size (int): Desired length of frames will be seen in the model.
|
||||
"""
|
||||
|
||||
def __init__(self, size):
|
||||
self.size = size
|
||||
|
||||
def __call__(self, total_frames):
|
||||
rand_end = max(0, total_frames - self.size - 1)
|
||||
begin_index = random.randint(0, rand_end)
|
||||
end_index = min(begin_index + self.size, total_frames)
|
||||
return begin_index, end_index
|
||||
|
||||
class DynamicSampleDuration(object):
|
||||
"""Temporally crop the given frame indices at a random location.
|
||||
|
||||
Args:
|
||||
size (int): Desired length of frames will be seen in the model.
|
||||
"""
|
||||
|
||||
def __init__(self, t_stride, extra_1):
|
||||
self.t_stride = t_stride
|
||||
self.extra_1 = extra_1
|
||||
|
||||
def __call__(self, t, h, w):
|
||||
if self.extra_1:
|
||||
t = t - 1
|
||||
truncate_t_list = list(range(t+1))[t//2:][::self.t_stride] # need half at least
|
||||
truncate_t = random.choice(truncate_t_list)
|
||||
if self.extra_1:
|
||||
truncate_t = truncate_t + 1
|
||||
return 0, truncate_t
|
||||
|
||||
if __name__ == '__main__':
|
||||
from torchvision import transforms
|
||||
import torchvision.io as io
|
||||
import numpy as np
|
||||
from torchvision.utils import save_image
|
||||
import os
|
||||
|
||||
vframes, aframes, info = io.read_video(
|
||||
filename='./v_Archery_g01_c03.avi',
|
||||
pts_unit='sec',
|
||||
output_format='TCHW'
|
||||
)
|
||||
|
||||
trans = transforms.Compose([
|
||||
ToTensorVideo(),
|
||||
RandomHorizontalFlipVideo(),
|
||||
UCFCenterCropVideo(512),
|
||||
# NormalizeVideo(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
|
||||
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True)
|
||||
])
|
||||
|
||||
target_video_len = 32
|
||||
frame_interval = 1
|
||||
total_frames = len(vframes)
|
||||
print(total_frames)
|
||||
|
||||
temporal_sample = TemporalRandomCrop(target_video_len * frame_interval)
|
||||
|
||||
# Sampling video frames
|
||||
start_frame_ind, end_frame_ind = temporal_sample(total_frames)
|
||||
# print(start_frame_ind)
|
||||
# print(end_frame_ind)
|
||||
assert end_frame_ind - start_frame_ind >= target_video_len
|
||||
frame_indice = np.linspace(start_frame_ind, end_frame_ind - 1, target_video_len, dtype=int)
|
||||
print(frame_indice)
|
||||
|
||||
select_vframes = vframes[frame_indice]
|
||||
print(select_vframes.shape)
|
||||
print(select_vframes.dtype)
|
||||
|
||||
select_vframes_trans = trans(select_vframes)
|
||||
print(select_vframes_trans.shape)
|
||||
print(select_vframes_trans.dtype)
|
||||
|
||||
select_vframes_trans_int = ((select_vframes_trans * 0.5 + 0.5) * 255).to(dtype=torch.uint8)
|
||||
print(select_vframes_trans_int.dtype)
|
||||
print(select_vframes_trans_int.permute(0, 2, 3, 1).shape)
|
||||
|
||||
io.write_video('./test.avi', select_vframes_trans_int.permute(0, 2, 3, 1), fps=8)
|
||||
|
||||
for i in range(target_video_len):
|
||||
save_image(select_vframes_trans[i], os.path.join('./test000', '%04d.png' % i), normalize=True,
|
||||
value_range=(-1, 1))
|
||||
+80
@@ -0,0 +1,80 @@
|
||||
import math
|
||||
import os
|
||||
|
||||
import decord
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchvision
|
||||
from decord import VideoReader, cpu
|
||||
from torch.utils.data import Dataset
|
||||
from torchvision.transforms import Compose, Lambda, ToTensor
|
||||
from torchvision.transforms._transforms_video import NormalizeVideo, RandomCropVideo, RandomHorizontalFlipVideo
|
||||
from pytorchvideo.transforms import ApplyTransformToKey, ShortSideScale, UniformTemporalSubsample
|
||||
from torch.nn import functional as F
|
||||
import random
|
||||
|
||||
from ..utils.dataset_utils import DecordInit
|
||||
|
||||
|
||||
class UCF101(Dataset):
|
||||
def __init__(self, args, transform, temporal_sample):
|
||||
self.data_path = args.data_path
|
||||
self.num_frames = args.num_frames
|
||||
self.transform = transform
|
||||
self.temporal_sample = temporal_sample
|
||||
self.v_decoder = DecordInit()
|
||||
|
||||
self.classes = sorted(os.listdir(self.data_path))
|
||||
self.class_to_idx = {cls_name: idx for idx, cls_name in enumerate(self.classes)}
|
||||
self.samples = self._make_dataset()
|
||||
|
||||
|
||||
def _make_dataset(self):
|
||||
dataset = []
|
||||
for class_name in self.classes:
|
||||
class_path = os.path.join(self.data_path, class_name)
|
||||
for fname in os.listdir(class_path):
|
||||
if fname.endswith('.avi'):
|
||||
item = (os.path.join(class_path, fname), self.class_to_idx[class_name])
|
||||
dataset.append(item)
|
||||
return dataset
|
||||
|
||||
def __len__(self):
|
||||
return len(self.samples)
|
||||
|
||||
def __getitem__(self, idx):
|
||||
video_path, label = self.samples[idx]
|
||||
try:
|
||||
video = self.tv_read(video_path)
|
||||
video = self.transform(video) # T C H W -> T C H W
|
||||
video = video.transpose(0, 1) # T C H W -> C T H W
|
||||
return video, label
|
||||
except Exception as e:
|
||||
print(f'Error with {e}, {video_path}')
|
||||
return self.__getitem__(random.randint(0, self.__len__()-1))
|
||||
|
||||
def tv_read(self, path):
|
||||
vframes, aframes, info = torchvision.io.read_video(filename=path, pts_unit='sec', output_format='TCHW')
|
||||
total_frames = len(vframes)
|
||||
|
||||
# Sampling video frames
|
||||
start_frame_ind, end_frame_ind = self.temporal_sample(total_frames)
|
||||
# assert end_frame_ind - start_frame_ind >= self.num_frames
|
||||
frame_indice = np.linspace(start_frame_ind, end_frame_ind - 1, self.num_frames, dtype=int)
|
||||
video = vframes[frame_indice] # (T, C, H, W)
|
||||
|
||||
return video
|
||||
|
||||
def decord_read(self, path):
|
||||
decord_vr = self.v_decoder(path)
|
||||
total_frames = len(decord_vr)
|
||||
# Sampling video frames
|
||||
start_frame_ind, end_frame_ind = self.temporal_sample(total_frames)
|
||||
# assert end_frame_ind - start_frame_ind >= self.num_frames
|
||||
frame_indice = np.linspace(start_frame_ind, end_frame_ind - 1, self.num_frames, dtype=int)
|
||||
|
||||
video_data = decord_vr.get_batch(frame_indice).asnumpy()
|
||||
video_data = torch.from_numpy(video_data)
|
||||
video_data = video_data.permute(0, 3, 1, 2) # (T, H, W, C) -> (T C H W)
|
||||
return video_data
|
||||
|
||||
+83
@@ -0,0 +1,83 @@
|
||||
import numpy as np
|
||||
import torch
|
||||
from tqdm import tqdm
|
||||
import math
|
||||
from einops import rearrange
|
||||
import sys
|
||||
sys.path.append(".")
|
||||
from flolpips.pwcnet import Network as PWCNet
|
||||
from flolpips.flolpips import FloLPIPS
|
||||
|
||||
loss_fn = FloLPIPS(net='alex', version='0.1').eval().requires_grad_(False)
|
||||
flownet = PWCNet().eval().requires_grad_(False)
|
||||
|
||||
def trans(x):
|
||||
return x
|
||||
|
||||
|
||||
def calculate_flolpips(videos1, videos2, device):
|
||||
global loss_fn, flownet
|
||||
|
||||
print("calculate_flowlpips...")
|
||||
loss_fn = loss_fn.to(device)
|
||||
flownet = flownet.to(device)
|
||||
|
||||
if videos1.shape != videos2.shape:
|
||||
print("Warning: the shape of videos are not equal.")
|
||||
min_frames = min(videos1.shape[1], videos2.shape[1])
|
||||
videos1 = videos1[:, :min_frames]
|
||||
videos2 = videos2[:, :min_frames]
|
||||
|
||||
videos1 = trans(videos1)
|
||||
videos2 = trans(videos2)
|
||||
|
||||
flolpips_results = []
|
||||
for video_num in tqdm(range(videos1.shape[0])):
|
||||
video1 = videos1[video_num].to(device)
|
||||
video2 = videos2[video_num].to(device)
|
||||
frames_rec = video1[:-1]
|
||||
frames_rec_next = video1[1:]
|
||||
frames_gt = video2[:-1]
|
||||
frames_gt_next = video2[1:]
|
||||
t, c, h, w = frames_gt.shape
|
||||
flow_gt = flownet(frames_gt, frames_gt_next)
|
||||
flow_dis = flownet(frames_rec, frames_rec_next)
|
||||
flow_diff = flow_gt - flow_dis
|
||||
flolpips = loss_fn.forward(frames_gt, frames_rec, flow_diff, normalize=True)
|
||||
flolpips_results.append(flolpips.cpu().numpy().tolist())
|
||||
|
||||
flolpips_results = np.array(flolpips_results) # [batch_size, num_frames]
|
||||
flolpips = {}
|
||||
flolpips_std = {}
|
||||
|
||||
for clip_timestamp in range(flolpips_results.shape[1]):
|
||||
flolpips[clip_timestamp] = np.mean(flolpips_results[:,clip_timestamp], axis=-1)
|
||||
flolpips_std[clip_timestamp] = np.std(flolpips_results[:,clip_timestamp], axis=-1)
|
||||
|
||||
result = {
|
||||
"value": flolpips,
|
||||
"value_std": flolpips_std,
|
||||
"video_setting": video1.shape,
|
||||
"video_setting_name": "time, channel, heigth, width",
|
||||
"result": flolpips_results,
|
||||
"details": flolpips_results.tolist()
|
||||
}
|
||||
|
||||
return result
|
||||
|
||||
# test code / using example
|
||||
|
||||
def main():
|
||||
NUMBER_OF_VIDEOS = 8
|
||||
VIDEO_LENGTH = 50
|
||||
CHANNEL = 3
|
||||
SIZE = 64
|
||||
videos1 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
videos2 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
|
||||
import json
|
||||
result = calculate_flolpips(videos1, videos2, "cuda:0")
|
||||
print(json.dumps(result, indent=4))
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
+85
@@ -0,0 +1,85 @@
|
||||
import numpy as np
|
||||
import torch
|
||||
from tqdm import tqdm
|
||||
|
||||
def trans(x):
|
||||
# if greyscale images add channel
|
||||
if x.shape[-3] == 1:
|
||||
x = x.repeat(1, 1, 3, 1, 1)
|
||||
|
||||
# permute BTCHW -> BCTHW
|
||||
x = x.permute(0, 2, 1, 3, 4)
|
||||
|
||||
return x
|
||||
|
||||
def calculate_fvd(videos1, videos2, device, method='styleganv'):
|
||||
|
||||
if method == 'styleganv':
|
||||
from fvd.styleganv.fvd import get_fvd_feats, frechet_distance, load_i3d_pretrained
|
||||
elif method == 'videogpt':
|
||||
from fvd.videogpt.fvd import load_i3d_pretrained
|
||||
from fvd.videogpt.fvd import get_fvd_logits as get_fvd_feats
|
||||
from fvd.videogpt.fvd import frechet_distance
|
||||
|
||||
print("calculate_fvd...")
|
||||
|
||||
# videos [batch_size, timestamps, channel, h, w]
|
||||
|
||||
assert videos1.shape == videos2.shape
|
||||
|
||||
i3d = load_i3d_pretrained(device=device)
|
||||
fvd_results = []
|
||||
|
||||
# support grayscale input, if grayscale -> channel*3
|
||||
# BTCHW -> BCTHW
|
||||
# videos -> [batch_size, channel, timestamps, h, w]
|
||||
|
||||
videos1 = trans(videos1)
|
||||
videos2 = trans(videos2)
|
||||
|
||||
fvd_results = {}
|
||||
|
||||
# for calculate FVD, each clip_timestamp must >= 10
|
||||
for clip_timestamp in tqdm(range(10, videos1.shape[-3]+1)):
|
||||
|
||||
# get a video clip
|
||||
# videos_clip [batch_size, channel, timestamps[:clip], h, w]
|
||||
videos_clip1 = videos1[:, :, : clip_timestamp]
|
||||
videos_clip2 = videos2[:, :, : clip_timestamp]
|
||||
|
||||
# get FVD features
|
||||
feats1 = get_fvd_feats(videos_clip1, i3d=i3d, device=device)
|
||||
feats2 = get_fvd_feats(videos_clip2, i3d=i3d, device=device)
|
||||
|
||||
# calculate FVD when timestamps[:clip]
|
||||
fvd_results[clip_timestamp] = frechet_distance(feats1, feats2)
|
||||
|
||||
result = {
|
||||
"value": fvd_results,
|
||||
"video_setting": videos1.shape,
|
||||
"video_setting_name": "batch_size, channel, time, heigth, width",
|
||||
}
|
||||
|
||||
return result
|
||||
|
||||
# test code / using example
|
||||
|
||||
def main():
|
||||
NUMBER_OF_VIDEOS = 8
|
||||
VIDEO_LENGTH = 50
|
||||
CHANNEL = 3
|
||||
SIZE = 64
|
||||
videos1 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
videos2 = torch.ones(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
device = torch.device("cuda")
|
||||
# device = torch.device("cpu")
|
||||
|
||||
import json
|
||||
result = calculate_fvd(videos1, videos2, device, method='videogpt')
|
||||
print(json.dumps(result, indent=4))
|
||||
|
||||
result = calculate_fvd(videos1, videos2, device, method='styleganv')
|
||||
print(json.dumps(result, indent=4))
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
+97
@@ -0,0 +1,97 @@
|
||||
import numpy as np
|
||||
import torch
|
||||
from tqdm import tqdm
|
||||
import math
|
||||
|
||||
import torch
|
||||
import lpips
|
||||
|
||||
spatial = True # Return a spatial map of perceptual distance.
|
||||
|
||||
# Linearly calibrated models (LPIPS)
|
||||
loss_fn = lpips.LPIPS(net='alex', spatial=spatial) # Can also set net = 'squeeze' or 'vgg'
|
||||
# loss_fn = lpips.LPIPS(net='alex', spatial=spatial, lpips=False) # Can also set net = 'squeeze' or 'vgg'
|
||||
|
||||
def trans(x):
|
||||
# if greyscale images add channel
|
||||
if x.shape[-3] == 1:
|
||||
x = x.repeat(1, 1, 3, 1, 1)
|
||||
|
||||
# value range [0, 1] -> [-1, 1]
|
||||
x = x * 2 - 1
|
||||
|
||||
return x
|
||||
|
||||
def calculate_lpips(videos1, videos2, device):
|
||||
# image should be RGB, IMPORTANT: normalized to [-1,1]
|
||||
print("calculate_lpips...")
|
||||
|
||||
assert videos1.shape == videos2.shape
|
||||
|
||||
# videos [batch_size, timestamps, channel, h, w]
|
||||
|
||||
# support grayscale input, if grayscale -> channel*3
|
||||
# value range [0, 1] -> [-1, 1]
|
||||
videos1 = trans(videos1)
|
||||
videos2 = trans(videos2)
|
||||
|
||||
lpips_results = []
|
||||
|
||||
for video_num in tqdm(range(videos1.shape[0])):
|
||||
# get a video
|
||||
# video [timestamps, channel, h, w]
|
||||
video1 = videos1[video_num]
|
||||
video2 = videos2[video_num]
|
||||
|
||||
lpips_results_of_a_video = []
|
||||
for clip_timestamp in range(len(video1)):
|
||||
# get a img
|
||||
# img [timestamps[x], channel, h, w]
|
||||
# img [channel, h, w] tensor
|
||||
|
||||
img1 = video1[clip_timestamp].unsqueeze(0).to(device)
|
||||
img2 = video2[clip_timestamp].unsqueeze(0).to(device)
|
||||
|
||||
loss_fn.to(device)
|
||||
|
||||
# calculate lpips of a video
|
||||
lpips_results_of_a_video.append(loss_fn.forward(img1, img2).mean().detach().cpu().tolist())
|
||||
lpips_results.append(lpips_results_of_a_video)
|
||||
|
||||
lpips_results = np.array(lpips_results)
|
||||
|
||||
lpips = {}
|
||||
lpips_std = {}
|
||||
|
||||
for clip_timestamp in range(len(video1)):
|
||||
lpips[clip_timestamp] = np.mean(lpips_results[:,clip_timestamp])
|
||||
lpips_std[clip_timestamp] = np.std(lpips_results[:,clip_timestamp])
|
||||
|
||||
|
||||
result = {
|
||||
"value": lpips,
|
||||
"value_std": lpips_std,
|
||||
"video_setting": video1.shape,
|
||||
"video_setting_name": "time, channel, heigth, width",
|
||||
}
|
||||
|
||||
return result
|
||||
|
||||
# test code / using example
|
||||
|
||||
def main():
|
||||
NUMBER_OF_VIDEOS = 8
|
||||
VIDEO_LENGTH = 50
|
||||
CHANNEL = 3
|
||||
SIZE = 64
|
||||
videos1 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
videos2 = torch.ones(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
device = torch.device("cuda")
|
||||
# device = torch.device("cpu")
|
||||
|
||||
import json
|
||||
result = calculate_lpips(videos1, videos2, device)
|
||||
print(json.dumps(result, indent=4))
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
+97
@@ -0,0 +1,97 @@
|
||||
import numpy as np
|
||||
import torch
|
||||
from tqdm import tqdm
|
||||
import math
|
||||
|
||||
def img_psnr_cuda(img1, img2):
|
||||
# [0,1]
|
||||
# compute mse
|
||||
# mse = np.mean((img1-img2)**2)
|
||||
mse = torch.mean((img1 / 1.0 - img2 / 1.0) ** 2)
|
||||
# compute psnr
|
||||
if mse < 1e-10:
|
||||
return 100
|
||||
psnr = 20 * torch.log10(1 / torch.sqrt(mse))
|
||||
return psnr
|
||||
|
||||
|
||||
def img_psnr(img1, img2):
|
||||
# [0,1]
|
||||
# compute mse
|
||||
# mse = np.mean((img1-img2)**2)
|
||||
mse = np.mean((img1 / 1.0 - img2 / 1.0) ** 2)
|
||||
# compute psnr
|
||||
if mse < 1e-10:
|
||||
return 100
|
||||
psnr = 20 * math.log10(1 / math.sqrt(mse))
|
||||
return psnr
|
||||
|
||||
|
||||
def trans(x):
|
||||
return x
|
||||
|
||||
def calculate_psnr(videos1, videos2):
|
||||
print("calculate_psnr...")
|
||||
|
||||
# videos [batch_size, timestamps, channel, h, w]
|
||||
|
||||
assert videos1.shape == videos2.shape
|
||||
|
||||
videos1 = trans(videos1)
|
||||
videos2 = trans(videos2)
|
||||
|
||||
psnr_results = []
|
||||
|
||||
for video_num in tqdm(range(videos1.shape[0])):
|
||||
# get a video
|
||||
# video [timestamps, channel, h, w]
|
||||
video1 = videos1[video_num]
|
||||
video2 = videos2[video_num]
|
||||
|
||||
psnr_results_of_a_video = []
|
||||
for clip_timestamp in range(len(video1)):
|
||||
# get a img
|
||||
# img [timestamps[x], channel, h, w]
|
||||
# img [channel, h, w] numpy
|
||||
|
||||
img1 = video1[clip_timestamp].numpy()
|
||||
img2 = video2[clip_timestamp].numpy()
|
||||
|
||||
# calculate psnr of a video
|
||||
psnr_results_of_a_video.append(img_psnr(img1, img2))
|
||||
|
||||
psnr_results.append(psnr_results_of_a_video)
|
||||
|
||||
psnr_results = np.array(psnr_results) # [batch_size, num_frames]
|
||||
psnr = {}
|
||||
psnr_std = {}
|
||||
|
||||
for clip_timestamp in range(len(video1)):
|
||||
psnr[clip_timestamp] = np.mean(psnr_results[:,clip_timestamp])
|
||||
psnr_std[clip_timestamp] = np.std(psnr_results[:,clip_timestamp])
|
||||
|
||||
result = {
|
||||
"value": psnr,
|
||||
"value_std": psnr_std,
|
||||
"video_setting": video1.shape,
|
||||
"video_setting_name": "time, channel, heigth, width",
|
||||
}
|
||||
|
||||
return result
|
||||
|
||||
# test code / using example
|
||||
|
||||
def main():
|
||||
NUMBER_OF_VIDEOS = 8
|
||||
VIDEO_LENGTH = 50
|
||||
CHANNEL = 3
|
||||
SIZE = 64
|
||||
videos1 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
videos2 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
|
||||
import json
|
||||
result = calculate_psnr(videos1, videos2)
|
||||
print(json.dumps(result, indent=4))
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
+113
@@ -0,0 +1,113 @@
|
||||
import numpy as np
|
||||
import torch
|
||||
from tqdm import tqdm
|
||||
import cv2
|
||||
|
||||
def ssim(img1, img2):
|
||||
C1 = 0.01 ** 2
|
||||
C2 = 0.03 ** 2
|
||||
img1 = img1.astype(np.float64)
|
||||
img2 = img2.astype(np.float64)
|
||||
kernel = cv2.getGaussianKernel(11, 1.5)
|
||||
window = np.outer(kernel, kernel.transpose())
|
||||
mu1 = cv2.filter2D(img1, -1, window)[5:-5, 5:-5] # valid
|
||||
mu2 = cv2.filter2D(img2, -1, window)[5:-5, 5:-5]
|
||||
mu1_sq = mu1 ** 2
|
||||
mu2_sq = mu2 ** 2
|
||||
mu1_mu2 = mu1 * mu2
|
||||
sigma1_sq = cv2.filter2D(img1 ** 2, -1, window)[5:-5, 5:-5] - mu1_sq
|
||||
sigma2_sq = cv2.filter2D(img2 ** 2, -1, window)[5:-5, 5:-5] - mu2_sq
|
||||
sigma12 = cv2.filter2D(img1 * img2, -1, window)[5:-5, 5:-5] - mu1_mu2
|
||||
ssim_map = ((2 * mu1_mu2 + C1) * (2 * sigma12 + C2)) / ((mu1_sq + mu2_sq + C1) *
|
||||
(sigma1_sq + sigma2_sq + C2))
|
||||
return ssim_map.mean()
|
||||
|
||||
|
||||
def calculate_ssim_function(img1, img2):
|
||||
# [0,1]
|
||||
# ssim is the only metric extremely sensitive to gray being compared to b/w
|
||||
if not img1.shape == img2.shape:
|
||||
raise ValueError('Input images must have the same dimensions.')
|
||||
if img1.ndim == 2:
|
||||
return ssim(img1, img2)
|
||||
elif img1.ndim == 3:
|
||||
if img1.shape[0] == 3:
|
||||
ssims = []
|
||||
for i in range(3):
|
||||
ssims.append(ssim(img1[i], img2[i]))
|
||||
return np.array(ssims).mean()
|
||||
elif img1.shape[0] == 1:
|
||||
return ssim(np.squeeze(img1), np.squeeze(img2))
|
||||
else:
|
||||
raise ValueError('Wrong input image dimensions.')
|
||||
|
||||
def trans(x):
|
||||
return x
|
||||
|
||||
def calculate_ssim(videos1, videos2):
|
||||
print("calculate_ssim...")
|
||||
|
||||
# videos [batch_size, timestamps, channel, h, w]
|
||||
|
||||
assert videos1.shape == videos2.shape
|
||||
|
||||
videos1 = trans(videos1)
|
||||
videos2 = trans(videos2)
|
||||
|
||||
ssim_results = []
|
||||
|
||||
for video_num in tqdm(range(videos1.shape[0])):
|
||||
# get a video
|
||||
# video [timestamps, channel, h, w]
|
||||
video1 = videos1[video_num]
|
||||
video2 = videos2[video_num]
|
||||
|
||||
ssim_results_of_a_video = []
|
||||
for clip_timestamp in range(len(video1)):
|
||||
# get a img
|
||||
# img [timestamps[x], channel, h, w]
|
||||
# img [channel, h, w] numpy
|
||||
|
||||
img1 = video1[clip_timestamp].numpy()
|
||||
img2 = video2[clip_timestamp].numpy()
|
||||
|
||||
# calculate ssim of a video
|
||||
ssim_results_of_a_video.append(calculate_ssim_function(img1, img2))
|
||||
|
||||
ssim_results.append(ssim_results_of_a_video)
|
||||
|
||||
ssim_results = np.array(ssim_results)
|
||||
|
||||
ssim = {}
|
||||
ssim_std = {}
|
||||
|
||||
for clip_timestamp in range(len(video1)):
|
||||
ssim[clip_timestamp] = np.mean(ssim_results[:,clip_timestamp])
|
||||
ssim_std[clip_timestamp] = np.std(ssim_results[:,clip_timestamp])
|
||||
|
||||
result = {
|
||||
"value": ssim,
|
||||
"value_std": ssim_std,
|
||||
"video_setting": video1.shape,
|
||||
"video_setting_name": "time, channel, heigth, width",
|
||||
}
|
||||
|
||||
return result
|
||||
|
||||
# test code / using example
|
||||
|
||||
def main():
|
||||
NUMBER_OF_VIDEOS = 8
|
||||
VIDEO_LENGTH = 50
|
||||
CHANNEL = 3
|
||||
SIZE = 64
|
||||
videos1 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
videos2 = torch.zeros(NUMBER_OF_VIDEOS, VIDEO_LENGTH, CHANNEL, SIZE, SIZE, requires_grad=False)
|
||||
device = torch.device("cuda")
|
||||
|
||||
import json
|
||||
result = calculate_ssim(videos1, videos2)
|
||||
print(json.dumps(result, indent=4))
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
+225
@@ -0,0 +1,225 @@
|
||||
"""Calculates the CLIP Scores
|
||||
|
||||
The CLIP model is a contrasitively learned language-image model. There is
|
||||
an image encoder and a text encoder. It is believed that the CLIP model could
|
||||
measure the similarity of cross modalities. Please find more information from
|
||||
https://github.com/openai/CLIP.
|
||||
|
||||
The CLIP Score measures the Cosine Similarity between two embedded features.
|
||||
This repository utilizes the pretrained CLIP Model to calculate
|
||||
the mean average of cosine similarities.
|
||||
|
||||
See --help to see further details.
|
||||
|
||||
Code apapted from https://github.com/mseitzer/pytorch-fid and https://github.com/openai/CLIP.
|
||||
|
||||
Copyright 2023 The Hong Kong Polytechnic University
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
"""
|
||||
import os
|
||||
import os.path as osp
|
||||
from argparse import ArgumentDefaultsHelpFormatter, ArgumentParser
|
||||
|
||||
import clip
|
||||
import torch
|
||||
from PIL import Image
|
||||
from torch.utils.data import Dataset, DataLoader
|
||||
|
||||
try:
|
||||
from tqdm import tqdm
|
||||
except ImportError:
|
||||
# If tqdm is not available, provide a mock version of it
|
||||
def tqdm(x):
|
||||
return x
|
||||
|
||||
|
||||
IMAGE_EXTENSIONS = {'bmp', 'jpg', 'jpeg', 'pgm', 'png', 'ppm',
|
||||
'tif', 'tiff', 'webp'}
|
||||
|
||||
TEXT_EXTENSIONS = {'txt'}
|
||||
|
||||
|
||||
class DummyDataset(Dataset):
|
||||
|
||||
FLAGS = ['img', 'txt']
|
||||
def __init__(self, real_path, generated_path,
|
||||
real_flag: str = 'img',
|
||||
generated_flag: str = 'img',
|
||||
transform = None,
|
||||
tokenizer = None) -> None:
|
||||
super().__init__()
|
||||
assert real_flag in self.FLAGS and generated_flag in self.FLAGS, \
|
||||
'CLIP Score only support modality of {}. However, get {} and {}'.format(
|
||||
self.FLAGS, real_flag, generated_flag
|
||||
)
|
||||
self.real_folder = self._combine_without_prefix(real_path)
|
||||
self.real_flag = real_flag
|
||||
self.fake_foler = self._combine_without_prefix(generated_path)
|
||||
self.generated_flag = generated_flag
|
||||
self.transform = transform
|
||||
self.tokenizer = tokenizer
|
||||
# assert self._check()
|
||||
|
||||
def __len__(self):
|
||||
return len(self.real_folder)
|
||||
|
||||
def __getitem__(self, index):
|
||||
if index >= len(self):
|
||||
raise IndexError
|
||||
real_path = self.real_folder[index]
|
||||
generated_path = self.fake_foler[index]
|
||||
real_data = self._load_modality(real_path, self.real_flag)
|
||||
fake_data = self._load_modality(generated_path, self.generated_flag)
|
||||
|
||||
sample = dict(real=real_data, fake=fake_data)
|
||||
return sample
|
||||
|
||||
def _load_modality(self, path, modality):
|
||||
if modality == 'img':
|
||||
data = self._load_img(path)
|
||||
elif modality == 'txt':
|
||||
data = self._load_txt(path)
|
||||
else:
|
||||
raise TypeError("Got unexpected modality: {}".format(modality))
|
||||
return data
|
||||
|
||||
def _load_img(self, path):
|
||||
img = Image.open(path)
|
||||
if self.transform is not None:
|
||||
img = self.transform(img)
|
||||
return img
|
||||
|
||||
def _load_txt(self, path):
|
||||
with open(path, 'r') as fp:
|
||||
data = fp.read()
|
||||
fp.close()
|
||||
if self.tokenizer is not None:
|
||||
data = self.tokenizer(data).squeeze()
|
||||
return data
|
||||
|
||||
def _check(self):
|
||||
for idx in range(len(self)):
|
||||
real_name = self.real_folder[idx].split('.')
|
||||
fake_name = self.fake_folder[idx].split('.')
|
||||
if fake_name != real_name:
|
||||
return False
|
||||
return True
|
||||
|
||||
def _combine_without_prefix(self, folder_path, prefix='.'):
|
||||
folder = []
|
||||
for name in os.listdir(folder_path):
|
||||
if name[0] == prefix:
|
||||
continue
|
||||
folder.append(osp.join(folder_path, name))
|
||||
folder.sort()
|
||||
return folder
|
||||
|
||||
|
||||
@torch.no_grad()
|
||||
def calculate_clip_score(dataloader, model, real_flag, generated_flag):
|
||||
score_acc = 0.
|
||||
sample_num = 0.
|
||||
logit_scale = model.logit_scale.exp()
|
||||
for batch_data in tqdm(dataloader):
|
||||
real = batch_data['real']
|
||||
real_features = forward_modality(model, real, real_flag)
|
||||
fake = batch_data['fake']
|
||||
fake_features = forward_modality(model, fake, generated_flag)
|
||||
|
||||
# normalize features
|
||||
real_features = real_features / real_features.norm(dim=1, keepdim=True).to(torch.float32)
|
||||
fake_features = fake_features / fake_features.norm(dim=1, keepdim=True).to(torch.float32)
|
||||
|
||||
# calculate scores
|
||||
# score = logit_scale * real_features @ fake_features.t()
|
||||
# score_acc += torch.diag(score).sum()
|
||||
score = logit_scale * (fake_features * real_features).sum()
|
||||
score_acc += score
|
||||
sample_num += real.shape[0]
|
||||
|
||||
return score_acc / sample_num
|
||||
|
||||
|
||||
def forward_modality(model, data, flag):
|
||||
device = next(model.parameters()).device
|
||||
if flag == 'img':
|
||||
features = model.encode_image(data.to(device))
|
||||
elif flag == 'txt':
|
||||
features = model.encode_text(data.to(device))
|
||||
else:
|
||||
raise TypeError
|
||||
return features
|
||||
|
||||
|
||||
def main():
|
||||
parser = ArgumentParser(formatter_class=ArgumentDefaultsHelpFormatter)
|
||||
parser.add_argument('--batch-size', type=int, default=50,
|
||||
help='Batch size to use')
|
||||
parser.add_argument('--clip-model', type=str, default='ViT-B/32',
|
||||
help='CLIP model to use')
|
||||
parser.add_argument('--num-workers', type=int, default=8,
|
||||
help=('Number of processes to use for data loading. '
|
||||
'Defaults to `min(8, num_cpus)`'))
|
||||
parser.add_argument('--device', type=str, default=None,
|
||||
help='Device to use. Like cuda, cuda:0 or cpu')
|
||||
parser.add_argument('--real_flag', type=str, default='img',
|
||||
help=('The modality of real path. '
|
||||
'Default to img'))
|
||||
parser.add_argument('--generated_flag', type=str, default='txt',
|
||||
help=('The modality of generated path. '
|
||||
'Default to txt'))
|
||||
parser.add_argument('--real_path', type=str,
|
||||
help=('Paths to the real images or '
|
||||
'to .npz statistic files'))
|
||||
parser.add_argument('--generated_path', type=str,
|
||||
help=('Paths to the generated images or '
|
||||
'to .npz statistic files'))
|
||||
args = parser.parse_args()
|
||||
|
||||
if args.device is None:
|
||||
device = torch.device('cuda' if (torch.cuda.is_available()) else 'cpu')
|
||||
else:
|
||||
device = torch.device(args.device)
|
||||
|
||||
if args.num_workers is None:
|
||||
try:
|
||||
num_cpus = len(os.sched_getaffinity(0))
|
||||
except AttributeError:
|
||||
# os.sched_getaffinity is not available under Windows, use
|
||||
# os.cpu_count instead (which may not return the *available* number
|
||||
# of CPUs).
|
||||
num_cpus = os.cpu_count()
|
||||
|
||||
num_workers = min(num_cpus, 8) if num_cpus is not None else 0
|
||||
else:
|
||||
num_workers = args.num_workers
|
||||
|
||||
print('Loading CLIP model: {}'.format(args.clip_model))
|
||||
model, preprocess = clip.load(args.clip_model, device=device)
|
||||
|
||||
dataset = DummyDataset(args.real_path, args.generated_path,
|
||||
args.real_flag, args.generated_flag,
|
||||
transform=preprocess, tokenizer=clip.tokenize)
|
||||
dataloader = DataLoader(dataset, args.batch_size,
|
||||
num_workers=num_workers, pin_memory=True)
|
||||
|
||||
print('Calculating CLIP Score:')
|
||||
clip_score = calculate_clip_score(dataloader, model,
|
||||
args.real_flag, args.generated_flag)
|
||||
clip_score = clip_score.cpu().item()
|
||||
print('CLIP Score: ', clip_score)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
main()
|
||||
+226
@@ -0,0 +1,226 @@
|
||||
"""Calculates the CLIP Scores
|
||||
|
||||
The CLIP model is a contrasitively learned language-image model. There is
|
||||
an image encoder and a text encoder. It is believed that the CLIP model could
|
||||
measure the similarity of cross modalities. Please find more information from
|
||||
https://github.com/openai/CLIP.
|
||||
|
||||
The CLIP Score measures the Cosine Similarity between two embedded features.
|
||||
This repository utilizes the pretrained CLIP Model to calculate
|
||||
the mean average of cosine similarities.
|
||||
|
||||
See --help to see further details.
|
||||
|
||||
Code apapted from https://github.com/mseitzer/pytorch-fid and https://github.com/openai/CLIP.
|
||||
|
||||
Copyright 2023 The Hong Kong Polytechnic University
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
You may obtain a copy of the License at
|
||||
|
||||
http://www.apache.org/licenses/LICENSE-2.0
|
||||
|
||||
Unless required by applicable law or agreed to in writing, software
|
||||
distributed under the License is distributed on an "AS IS" BASIS,
|
||||
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
"""
|
||||
|
||||
import os
|
||||
import os.path as osp
|
||||
from argparse import ArgumentDefaultsHelpFormatter, ArgumentParser
|
||||
import numpy as np
|
||||
import torch
|
||||
from torch.utils.data import Dataset, DataLoader, Subset
|
||||
from decord import VideoReader, cpu
|
||||
import random
|
||||
from pytorchvideo.transforms import ShortSideScale
|
||||
from torchvision.io import read_video
|
||||
from torchvision.transforms import Lambda, Compose
|
||||
from torchvision.transforms._transforms_video import CenterCropVideo
|
||||
from cal_lpips import calculate_lpips
|
||||
from cal_fvd import calculate_fvd
|
||||
from cal_psnr import calculate_psnr
|
||||
from cal_flolpips import calculate_flolpips
|
||||
from cal_ssim import calculate_ssim
|
||||
try:
|
||||
from tqdm import tqdm
|
||||
except ImportError:
|
||||
# If tqdm is not available, provide a mock version of it
|
||||
def tqdm(x):
|
||||
return x
|
||||
|
||||
class VideoDataset(Dataset):
|
||||
def __init__(self,
|
||||
real_video_dir,
|
||||
generated_video_dir,
|
||||
num_frames,
|
||||
sample_rate = 1,
|
||||
crop_size=None,
|
||||
resolution=128,
|
||||
) -> None:
|
||||
super().__init__()
|
||||
self.real_video_files = []
|
||||
self.generated_video_files = self._combine_without_prefix(generated_video_dir)
|
||||
for video_file in self.generated_video_files:
|
||||
filename = os.path.basename(video_file)
|
||||
self.real_video_files.append(os.path.join(real_video_dir, filename))
|
||||
self.num_frames = num_frames
|
||||
self.sample_rate = sample_rate
|
||||
self.crop_size = crop_size
|
||||
self.short_size = resolution
|
||||
|
||||
|
||||
def __len__(self):
|
||||
return len(self.real_video_files)
|
||||
|
||||
def __getitem__(self, index):
|
||||
if index >= len(self):
|
||||
raise IndexError
|
||||
real_video_file = self.real_video_files[index]
|
||||
generated_video_file = self.generated_video_files[index]
|
||||
real_video_tensor = self._load_video(real_video_file, self.sample_rate)
|
||||
generated_video_tensor = self._load_video(generated_video_file, 1)
|
||||
return {'real': real_video_tensor, 'generated':generated_video_tensor }
|
||||
|
||||
|
||||
def _load_video(self, video_path, sample_rate):
|
||||
num_frames = self.num_frames
|
||||
decord_vr = VideoReader(video_path, ctx=cpu(0))
|
||||
total_frames = len(decord_vr)
|
||||
sample_frames_len = sample_rate * num_frames
|
||||
|
||||
if total_frames >= sample_frames_len:
|
||||
s = 0
|
||||
e = s + sample_frames_len
|
||||
num_frames = num_frames
|
||||
else:
|
||||
s = 0
|
||||
e = total_frames
|
||||
num_frames = int(total_frames / sample_frames_len * num_frames)
|
||||
print(f'sample_frames_len {sample_frames_len}, only can sample {num_frames * sample_rate}', video_path,
|
||||
total_frames)
|
||||
|
||||
|
||||
frame_id_list = np.linspace(s, e - 1, num_frames, dtype=int)
|
||||
video_data = decord_vr.get_batch(frame_id_list).asnumpy()
|
||||
video_data = torch.from_numpy(video_data)
|
||||
video_data = video_data.permute(0, 3, 1, 2) # (T, H, W, C) -> (C, T, H, W)
|
||||
return _preprocess(video_data, short_size=self.short_size, crop_size = self.crop_size)
|
||||
|
||||
|
||||
def _combine_without_prefix(self, folder_path, prefix='.'):
|
||||
folder = []
|
||||
os.makedirs(folder_path, exist_ok=True)
|
||||
for name in os.listdir(folder_path):
|
||||
if name[0] == prefix:
|
||||
continue
|
||||
if osp.isfile(osp.join(folder_path, name)):
|
||||
folder.append(osp.join(folder_path, name))
|
||||
folder.sort()
|
||||
return folder
|
||||
|
||||
def _preprocess(video_data, short_size=128, crop_size=None):
|
||||
transform = Compose(
|
||||
[
|
||||
Lambda(lambda x: x / 255.0),
|
||||
ShortSideScale(size=short_size),
|
||||
CenterCropVideo(crop_size=crop_size),
|
||||
]
|
||||
)
|
||||
video_outputs = transform(video_data)
|
||||
# video_outputs = torch.unsqueeze(video_outputs, 0) # (bz,c,t,h,w)
|
||||
return video_outputs
|
||||
|
||||
|
||||
def calculate_common_metric(args, dataloader, device):
|
||||
|
||||
score_list = []
|
||||
for batch_data in tqdm(dataloader): # {'real': real_video_tensor, 'generated':generated_video_tensor }
|
||||
real_videos = batch_data['real']
|
||||
generated_videos = batch_data['generated']
|
||||
|
||||
assert real_videos.shape[2] == generated_videos.shape[2]
|
||||
if args.metric == 'fvd':
|
||||
tmp_list = list(calculate_fvd(real_videos, generated_videos, args.device, method=args.fvd_method)['value'].values())
|
||||
elif args.metric == 'ssim':
|
||||
tmp_list = list(calculate_ssim(real_videos, generated_videos)['value'].values())
|
||||
elif args.metric == 'psnr':
|
||||
tmp_list = list(calculate_psnr(real_videos, generated_videos)['value'].values())
|
||||
elif args.metric == 'flolpips':
|
||||
result = calculate_flolpips(real_videos, generated_videos, args.device)
|
||||
tmp_list = list(result['value'].values())
|
||||
elif args.metric == 'wraperror':
|
||||
result = calculate_wraperror(real_videos, generated_videos, args.device)
|
||||
tmp_list = list(result['value'].values())
|
||||
else:
|
||||
tmp_list = list(calculate_lpips(real_videos, generated_videos, args.device)['value'].values())
|
||||
score_list += tmp_list
|
||||
return np.mean(score_list)
|
||||
|
||||
def main():
|
||||
parser = ArgumentParser(formatter_class=ArgumentDefaultsHelpFormatter)
|
||||
parser.add_argument('--batch_size', type=int, default=2,
|
||||
help='Batch size to use')
|
||||
parser.add_argument('--real_video_dir', type=str,
|
||||
help=('the path of real videos`'))
|
||||
parser.add_argument('--generated_video_dir', type=str,
|
||||
help=('the path of generated videos`'))
|
||||
parser.add_argument('--device', type=str, default=None,
|
||||
help='Device to use. Like cuda, cuda:0 or cpu')
|
||||
parser.add_argument('--num_workers', type=int, default=8,
|
||||
help=('Number of processes to use for data loading. '
|
||||
'Defaults to `min(8, num_cpus)`'))
|
||||
parser.add_argument('--sample_fps', type=int, default=30)
|
||||
parser.add_argument('--resolution', type=int, default=336)
|
||||
parser.add_argument('--crop_size', type=int, default=None)
|
||||
parser.add_argument('--num_frames', type=int, default=100)
|
||||
parser.add_argument('--sample_rate', type=int, default=1)
|
||||
parser.add_argument('--subset_size', type=int, default=None)
|
||||
parser.add_argument("--metric", type=str, default="fvd",choices=['fvd','psnr','ssim','lpips', 'flolpips'])
|
||||
parser.add_argument("--fvd_method", type=str, default='styleganv',choices=['styleganv','videogpt'])
|
||||
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
if args.device is None:
|
||||
device = torch.device('cuda:1' if (torch.cuda.is_available()) else 'cpu')
|
||||
else:
|
||||
device = torch.device(args.device)
|
||||
|
||||
if args.num_workers is None:
|
||||
try:
|
||||
num_cpus = len(os.sched_getaffinity(0))
|
||||
except AttributeError:
|
||||
# os.sched_getaffinity is not available under Windows, use
|
||||
# os.cpu_count instead (which may not return the *available* number
|
||||
# of CPUs).
|
||||
num_cpus = os.cpu_count()
|
||||
|
||||
num_workers = min(num_cpus, 8) if num_cpus is not None else 0
|
||||
else:
|
||||
num_workers = args.num_workers
|
||||
|
||||
|
||||
dataset = VideoDataset(args.real_video_dir,
|
||||
args.generated_video_dir,
|
||||
num_frames = args.num_frames,
|
||||
sample_rate = args.sample_rate,
|
||||
crop_size=args.crop_size,
|
||||
resolution=args.resolution)
|
||||
|
||||
if args.subset_size:
|
||||
indices = range(args.subset_size)
|
||||
dataset = Subset(dataset, indices=indices)
|
||||
|
||||
dataloader = DataLoader(dataset, args.batch_size,
|
||||
num_workers=num_workers, pin_memory=True)
|
||||
|
||||
|
||||
metric_score = calculate_common_metric(args, dataloader,device)
|
||||
print('metric: ', args.metric, " ",metric_score)
|
||||
|
||||
if __name__ == '__main__':
|
||||
main()
|
||||
@@ -0,0 +1,397 @@
|
||||
#!/usr/bin/env python
|
||||
|
||||
import torch
|
||||
|
||||
import cupy#add
|
||||
import re
|
||||
|
||||
kernel_Correlation_rearrange = '''
|
||||
extern "C" __global__ void kernel_Correlation_rearrange(
|
||||
const int n,
|
||||
const float* input,
|
||||
float* output
|
||||
) {
|
||||
int intIndex = (blockIdx.x * blockDim.x) + threadIdx.x;
|
||||
|
||||
if (intIndex >= n) {
|
||||
return;
|
||||
}
|
||||
|
||||
int intSample = blockIdx.z;
|
||||
int intChannel = blockIdx.y;
|
||||
|
||||
float fltValue = input[(((intSample * SIZE_1(input)) + intChannel) * SIZE_2(input) * SIZE_3(input)) + intIndex];
|
||||
|
||||
__syncthreads();
|
||||
|
||||
int intPaddedY = (intIndex / SIZE_3(input)) + 4;
|
||||
int intPaddedX = (intIndex % SIZE_3(input)) + 4;
|
||||
int intRearrange = ((SIZE_3(input) + 8) * intPaddedY) + intPaddedX;
|
||||
|
||||
output[(((intSample * SIZE_1(output) * SIZE_2(output)) + intRearrange) * SIZE_1(input)) + intChannel] = fltValue;
|
||||
}
|
||||
'''
|
||||
|
||||
kernel_Correlation_updateOutput = '''
|
||||
extern "C" __global__ void kernel_Correlation_updateOutput(
|
||||
const int n,
|
||||
const float* rbot0,
|
||||
const float* rbot1,
|
||||
float* top
|
||||
) {
|
||||
extern __shared__ char patch_data_char[];
|
||||
|
||||
float *patch_data = (float *)patch_data_char;
|
||||
|
||||
// First (upper left) position of kernel upper-left corner in current center position of neighborhood in image 1
|
||||
int x1 = blockIdx.x + 4;
|
||||
int y1 = blockIdx.y + 4;
|
||||
int item = blockIdx.z;
|
||||
int ch_off = threadIdx.x;
|
||||
|
||||
// Load 3D patch into shared shared memory
|
||||
for (int j = 0; j < 1; j++) { // HEIGHT
|
||||
for (int i = 0; i < 1; i++) { // WIDTH
|
||||
int ji_off = (j + i) * SIZE_3(rbot0);
|
||||
for (int ch = ch_off; ch < SIZE_3(rbot0); ch += 32) { // CHANNELS
|
||||
int idx1 = ((item * SIZE_1(rbot0) + y1+j) * SIZE_2(rbot0) + x1+i) * SIZE_3(rbot0) + ch;
|
||||
int idxPatchData = ji_off + ch;
|
||||
patch_data[idxPatchData] = rbot0[idx1];
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
__syncthreads();
|
||||
|
||||
__shared__ float sum[32];
|
||||
|
||||
// Compute correlation
|
||||
for (int top_channel = 0; top_channel < SIZE_1(top); top_channel++) {
|
||||
sum[ch_off] = 0;
|
||||
|
||||
int s2o = top_channel % 9 - 4;
|
||||
int s2p = top_channel / 9 - 4;
|
||||
|
||||
for (int j = 0; j < 1; j++) { // HEIGHT
|
||||
for (int i = 0; i < 1; i++) { // WIDTH
|
||||
int ji_off = (j + i) * SIZE_3(rbot0);
|
||||
for (int ch = ch_off; ch < SIZE_3(rbot0); ch += 32) { // CHANNELS
|
||||
int x2 = x1 + s2o;
|
||||
int y2 = y1 + s2p;
|
||||
|
||||
int idxPatchData = ji_off + ch;
|
||||
int idx2 = ((item * SIZE_1(rbot0) + y2+j) * SIZE_2(rbot0) + x2+i) * SIZE_3(rbot0) + ch;
|
||||
|
||||
sum[ch_off] += patch_data[idxPatchData] * rbot1[idx2];
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
__syncthreads();
|
||||
|
||||
if (ch_off == 0) {
|
||||
float total_sum = 0;
|
||||
for (int idx = 0; idx < 32; idx++) {
|
||||
total_sum += sum[idx];
|
||||
}
|
||||
const int sumelems = SIZE_3(rbot0);
|
||||
const int index = ((top_channel*SIZE_2(top) + blockIdx.y)*SIZE_3(top))+blockIdx.x;
|
||||
top[index + item*SIZE_1(top)*SIZE_2(top)*SIZE_3(top)] = total_sum / (float)sumelems;
|
||||
}
|
||||
}
|
||||
}
|
||||
'''
|
||||
|
||||
kernel_Correlation_updateGradFirst = '''
|
||||
#define ROUND_OFF 50000
|
||||
|
||||
extern "C" __global__ void kernel_Correlation_updateGradFirst(
|
||||
const int n,
|
||||
const int intSample,
|
||||
const float* rbot0,
|
||||
const float* rbot1,
|
||||
const float* gradOutput,
|
||||
float* gradFirst,
|
||||
float* gradSecond
|
||||
) { for (int intIndex = (blockIdx.x * blockDim.x) + threadIdx.x; intIndex < n; intIndex += blockDim.x * gridDim.x) {
|
||||
int n = intIndex % SIZE_1(gradFirst); // channels
|
||||
int l = (intIndex / SIZE_1(gradFirst)) % SIZE_3(gradFirst) + 4; // w-pos
|
||||
int m = (intIndex / SIZE_1(gradFirst) / SIZE_3(gradFirst)) % SIZE_2(gradFirst) + 4; // h-pos
|
||||
|
||||
// round_off is a trick to enable integer division with ceil, even for negative numbers
|
||||
// We use a large offset, for the inner part not to become negative.
|
||||
const int round_off = ROUND_OFF;
|
||||
const int round_off_s1 = round_off;
|
||||
|
||||
// We add round_off before_s1 the int division and subtract round_off after it, to ensure the formula matches ceil behavior:
|
||||
int xmin = (l - 4 + round_off_s1 - 1) + 1 - round_off; // ceil (l - 4)
|
||||
int ymin = (m - 4 + round_off_s1 - 1) + 1 - round_off; // ceil (l - 4)
|
||||
|
||||
// Same here:
|
||||
int xmax = (l - 4 + round_off_s1) - round_off; // floor (l - 4)
|
||||
int ymax = (m - 4 + round_off_s1) - round_off; // floor (m - 4)
|
||||
|
||||
float sum = 0;
|
||||
if (xmax>=0 && ymax>=0 && (xmin<=SIZE_3(gradOutput)-1) && (ymin<=SIZE_2(gradOutput)-1)) {
|
||||
xmin = max(0,xmin);
|
||||
xmax = min(SIZE_3(gradOutput)-1,xmax);
|
||||
|
||||
ymin = max(0,ymin);
|
||||
ymax = min(SIZE_2(gradOutput)-1,ymax);
|
||||
|
||||
for (int p = -4; p <= 4; p++) {
|
||||
for (int o = -4; o <= 4; o++) {
|
||||
// Get rbot1 data:
|
||||
int s2o = o;
|
||||
int s2p = p;
|
||||
int idxbot1 = ((intSample * SIZE_1(rbot0) + (m+s2p)) * SIZE_2(rbot0) + (l+s2o)) * SIZE_3(rbot0) + n;
|
||||
float bot1tmp = rbot1[idxbot1]; // rbot1[l+s2o,m+s2p,n]
|
||||
|
||||
// Index offset for gradOutput in following loops:
|
||||
int op = (p+4) * 9 + (o+4); // index[o,p]
|
||||
int idxopoffset = (intSample * SIZE_1(gradOutput) + op);
|
||||
|
||||
for (int y = ymin; y <= ymax; y++) {
|
||||
for (int x = xmin; x <= xmax; x++) {
|
||||
int idxgradOutput = (idxopoffset * SIZE_2(gradOutput) + y) * SIZE_3(gradOutput) + x; // gradOutput[x,y,o,p]
|
||||
sum += gradOutput[idxgradOutput] * bot1tmp;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
const int sumelems = SIZE_1(gradFirst);
|
||||
const int bot0index = ((n * SIZE_2(gradFirst)) + (m-4)) * SIZE_3(gradFirst) + (l-4);
|
||||
gradFirst[bot0index + intSample*SIZE_1(gradFirst)*SIZE_2(gradFirst)*SIZE_3(gradFirst)] = sum / (float)sumelems;
|
||||
} }
|
||||
'''
|
||||
|
||||
kernel_Correlation_updateGradSecond = '''
|
||||
#define ROUND_OFF 50000
|
||||
|
||||
extern "C" __global__ void kernel_Correlation_updateGradSecond(
|
||||
const int n,
|
||||
const int intSample,
|
||||
const float* rbot0,
|
||||
const float* rbot1,
|
||||
const float* gradOutput,
|
||||
float* gradFirst,
|
||||
float* gradSecond
|
||||
) { for (int intIndex = (blockIdx.x * blockDim.x) + threadIdx.x; intIndex < n; intIndex += blockDim.x * gridDim.x) {
|
||||
int n = intIndex % SIZE_1(gradSecond); // channels
|
||||
int l = (intIndex / SIZE_1(gradSecond)) % SIZE_3(gradSecond) + 4; // w-pos
|
||||
int m = (intIndex / SIZE_1(gradSecond) / SIZE_3(gradSecond)) % SIZE_2(gradSecond) + 4; // h-pos
|
||||
|
||||
// round_off is a trick to enable integer division with ceil, even for negative numbers
|
||||
// We use a large offset, for the inner part not to become negative.
|
||||
const int round_off = ROUND_OFF;
|
||||
const int round_off_s1 = round_off;
|
||||
|
||||
float sum = 0;
|
||||
for (int p = -4; p <= 4; p++) {
|
||||
for (int o = -4; o <= 4; o++) {
|
||||
int s2o = o;
|
||||
int s2p = p;
|
||||
|
||||
//Get X,Y ranges and clamp
|
||||
// We add round_off before_s1 the int division and subtract round_off after it, to ensure the formula matches ceil behavior:
|
||||
int xmin = (l - 4 - s2o + round_off_s1 - 1) + 1 - round_off; // ceil (l - 4 - s2o)
|
||||
int ymin = (m - 4 - s2p + round_off_s1 - 1) + 1 - round_off; // ceil (l - 4 - s2o)
|
||||
|
||||
// Same here:
|
||||
int xmax = (l - 4 - s2o + round_off_s1) - round_off; // floor (l - 4 - s2o)
|
||||
int ymax = (m - 4 - s2p + round_off_s1) - round_off; // floor (m - 4 - s2p)
|
||||
|
||||
if (xmax>=0 && ymax>=0 && (xmin<=SIZE_3(gradOutput)-1) && (ymin<=SIZE_2(gradOutput)-1)) {
|
||||
xmin = max(0,xmin);
|
||||
xmax = min(SIZE_3(gradOutput)-1,xmax);
|
||||
|
||||
ymin = max(0,ymin);
|
||||
ymax = min(SIZE_2(gradOutput)-1,ymax);
|
||||
|
||||
// Get rbot0 data:
|
||||
int idxbot0 = ((intSample * SIZE_1(rbot0) + (m-s2p)) * SIZE_2(rbot0) + (l-s2o)) * SIZE_3(rbot0) + n;
|
||||
float bot0tmp = rbot0[idxbot0]; // rbot1[l+s2o,m+s2p,n]
|
||||
|
||||
// Index offset for gradOutput in following loops:
|
||||
int op = (p+4) * 9 + (o+4); // index[o,p]
|
||||
int idxopoffset = (intSample * SIZE_1(gradOutput) + op);
|
||||
|
||||
for (int y = ymin; y <= ymax; y++) {
|
||||
for (int x = xmin; x <= xmax; x++) {
|
||||
int idxgradOutput = (idxopoffset * SIZE_2(gradOutput) + y) * SIZE_3(gradOutput) + x; // gradOutput[x,y,o,p]
|
||||
sum += gradOutput[idxgradOutput] * bot0tmp;
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
const int sumelems = SIZE_1(gradSecond);
|
||||
const int bot1index = ((n * SIZE_2(gradSecond)) + (m-4)) * SIZE_3(gradSecond) + (l-4);
|
||||
gradSecond[bot1index + intSample*SIZE_1(gradSecond)*SIZE_2(gradSecond)*SIZE_3(gradSecond)] = sum / (float)sumelems;
|
||||
} }
|
||||
'''
|
||||
|
||||
def cupy_kernel(strFunction, objVariables):
|
||||
strKernel = globals()[strFunction]
|
||||
|
||||
while True:
|
||||
objMatch = re.search('(SIZE_)([0-4])(\()([^\)]*)(\))', strKernel)
|
||||
|
||||
if objMatch is None:
|
||||
break
|
||||
# end
|
||||
|
||||
intArg = int(objMatch.group(2))
|
||||
|
||||
strTensor = objMatch.group(4)
|
||||
intSizes = objVariables[strTensor].size()
|
||||
|
||||
strKernel = strKernel.replace(objMatch.group(), str(intSizes[intArg]))
|
||||
# end
|
||||
|
||||
while True:
|
||||
objMatch = re.search('(VALUE_)([0-4])(\()([^\)]+)(\))', strKernel)
|
||||
|
||||
if objMatch is None:
|
||||
break
|
||||
# end
|
||||
|
||||
intArgs = int(objMatch.group(2))
|
||||
strArgs = objMatch.group(4).split(',')
|
||||
|
||||
strTensor = strArgs[0]
|
||||
intStrides = objVariables[strTensor].stride()
|
||||
strIndex = [ '((' + strArgs[intArg + 1].replace('{', '(').replace('}', ')').strip() + ')*' + str(intStrides[intArg]) + ')' for intArg in range(intArgs) ]
|
||||
|
||||
strKernel = strKernel.replace(objMatch.group(0), strTensor + '[' + str.join('+', strIndex) + ']')
|
||||
# end
|
||||
|
||||
return strKernel
|
||||
# end
|
||||
|
||||
@cupy.memoize(for_each_device=True)
|
||||
def cupy_launch(strFunction, strKernel):
|
||||
return cupy.RawKernel(strKernel, strFunction)
|
||||
# end
|
||||
|
||||
class _FunctionCorrelation(torch.autograd.Function):
|
||||
@staticmethod
|
||||
def forward(self, first, second):
|
||||
rbot0 = first.new_zeros([ first.shape[0], first.shape[2] + 8, first.shape[3] + 8, first.shape[1] ])
|
||||
rbot1 = first.new_zeros([ first.shape[0], first.shape[2] + 8, first.shape[3] + 8, first.shape[1] ])
|
||||
|
||||
self.save_for_backward(first, second, rbot0, rbot1)
|
||||
|
||||
first = first.contiguous(); assert(first.is_cuda == True)
|
||||
second = second.contiguous(); assert(second.is_cuda == True)
|
||||
|
||||
output = first.new_zeros([ first.shape[0], 81, first.shape[2], first.shape[3] ])
|
||||
|
||||
if first.is_cuda == True:
|
||||
n = first.shape[2] * first.shape[3]
|
||||
cupy_launch('kernel_Correlation_rearrange', cupy_kernel('kernel_Correlation_rearrange', {
|
||||
'input': first,
|
||||
'output': rbot0
|
||||
}))(
|
||||
grid=tuple([ int((n + 16 - 1) / 16), first.shape[1], first.shape[0] ]),
|
||||
block=tuple([ 16, 1, 1 ]),
|
||||
args=[ n, first.data_ptr(), rbot0.data_ptr() ]
|
||||
)
|
||||
|
||||
n = second.shape[2] * second.shape[3]
|
||||
cupy_launch('kernel_Correlation_rearrange', cupy_kernel('kernel_Correlation_rearrange', {
|
||||
'input': second,
|
||||
'output': rbot1
|
||||
}))(
|
||||
grid=tuple([ int((n + 16 - 1) / 16), second.shape[1], second.shape[0] ]),
|
||||
block=tuple([ 16, 1, 1 ]),
|
||||
args=[ n, second.data_ptr(), rbot1.data_ptr() ]
|
||||
)
|
||||
|
||||
n = output.shape[1] * output.shape[2] * output.shape[3]
|
||||
cupy_launch('kernel_Correlation_updateOutput', cupy_kernel('kernel_Correlation_updateOutput', {
|
||||
'rbot0': rbot0,
|
||||
'rbot1': rbot1,
|
||||
'top': output
|
||||
}))(
|
||||
grid=tuple([ output.shape[3], output.shape[2], output.shape[0] ]),
|
||||
block=tuple([ 32, 1, 1 ]),
|
||||
shared_mem=first.shape[1] * 4,
|
||||
args=[ n, rbot0.data_ptr(), rbot1.data_ptr(), output.data_ptr() ]
|
||||
)
|
||||
|
||||
elif first.is_cuda == False:
|
||||
raise NotImplementedError()
|
||||
|
||||
# end
|
||||
|
||||
return output
|
||||
# end
|
||||
|
||||
@staticmethod
|
||||
def backward(self, gradOutput):
|
||||
first, second, rbot0, rbot1 = self.saved_tensors
|
||||
|
||||
gradOutput = gradOutput.contiguous(); assert(gradOutput.is_cuda == True)
|
||||
|
||||
gradFirst = first.new_zeros([ first.shape[0], first.shape[1], first.shape[2], first.shape[3] ]) if self.needs_input_grad[0] == True else None
|
||||
gradSecond = first.new_zeros([ first.shape[0], first.shape[1], first.shape[2], first.shape[3] ]) if self.needs_input_grad[1] == True else None
|
||||
|
||||
if first.is_cuda == True:
|
||||
if gradFirst is not None:
|
||||
for intSample in range(first.shape[0]):
|
||||
n = first.shape[1] * first.shape[2] * first.shape[3]
|
||||
cupy_launch('kernel_Correlation_updateGradFirst', cupy_kernel('kernel_Correlation_updateGradFirst', {
|
||||
'rbot0': rbot0,
|
||||
'rbot1': rbot1,
|
||||
'gradOutput': gradOutput,
|
||||
'gradFirst': gradFirst,
|
||||
'gradSecond': None
|
||||
}))(
|
||||
grid=tuple([ int((n + 512 - 1) / 512), 1, 1 ]),
|
||||
block=tuple([ 512, 1, 1 ]),
|
||||
args=[ n, intSample, rbot0.data_ptr(), rbot1.data_ptr(), gradOutput.data_ptr(), gradFirst.data_ptr(), None ]
|
||||
)
|
||||
# end
|
||||
# end
|
||||
|
||||
if gradSecond is not None:
|
||||
for intSample in range(first.shape[0]):
|
||||
n = first.shape[1] * first.shape[2] * first.shape[3]
|
||||
cupy_launch('kernel_Correlation_updateGradSecond', cupy_kernel('kernel_Correlation_updateGradSecond', {
|
||||
'rbot0': rbot0,
|
||||
'rbot1': rbot1,
|
||||
'gradOutput': gradOutput,
|
||||
'gradFirst': None,
|
||||
'gradSecond': gradSecond
|
||||
}))(
|
||||
grid=tuple([ int((n + 512 - 1) / 512), 1, 1 ]),
|
||||
block=tuple([ 512, 1, 1 ]),
|
||||
args=[ n, intSample, rbot0.data_ptr(), rbot1.data_ptr(), gradOutput.data_ptr(), None, gradSecond.data_ptr() ]
|
||||
)
|
||||
# end
|
||||
# end
|
||||
|
||||
elif first.is_cuda == False:
|
||||
raise NotImplementedError()
|
||||
|
||||
# end
|
||||
|
||||
return gradFirst, gradSecond
|
||||
# end
|
||||
# end
|
||||
|
||||
def FunctionCorrelation(tenFirst, tenSecond):
|
||||
return _FunctionCorrelation.apply(tenFirst, tenSecond)
|
||||
# end
|
||||
|
||||
class ModuleCorrelation(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super(ModuleCorrelation, self).__init__()
|
||||
# end
|
||||
|
||||
def forward(self, tenFirst, tenSecond):
|
||||
return _FunctionCorrelation.apply(tenFirst, tenSecond)
|
||||
# end
|
||||
# end
|
||||
+308
@@ -0,0 +1,308 @@
|
||||
|
||||
from __future__ import absolute_import
|
||||
import os
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from torch.autograd import Variable
|
||||
from .pretrained_networks import vgg16, alexnet, squeezenet
|
||||
import torch.nn
|
||||
import torch.nn.functional as F
|
||||
import torchvision.transforms.functional as TF
|
||||
import cv2
|
||||
|
||||
from .pwcnet import Network as PWCNet
|
||||
from .utils import *
|
||||
|
||||
def spatial_average(in_tens, keepdim=True):
|
||||
return in_tens.mean([2,3],keepdim=keepdim)
|
||||
|
||||
def mw_spatial_average(in_tens, flow, keepdim=True):
|
||||
_,_,h,w = in_tens.shape
|
||||
flow = F.interpolate(flow, (h,w), align_corners=False, mode='bilinear')
|
||||
flow_mag = torch.sqrt(flow[:,0:1]**2 + flow[:,1:2]**2)
|
||||
flow_mag = flow_mag / torch.sum(flow_mag, dim=[1,2,3], keepdim=True)
|
||||
return torch.sum(in_tens*flow_mag, dim=[2,3],keepdim=keepdim)
|
||||
|
||||
|
||||
def mtw_spatial_average(in_tens, flow, texture, keepdim=True):
|
||||
_,_,h,w = in_tens.shape
|
||||
flow = F.interpolate(flow, (h,w), align_corners=False, mode='bilinear')
|
||||
texture = F.interpolate(texture, (h,w), align_corners=False, mode='bilinear')
|
||||
flow_mag = torch.sqrt(flow[:,0:1]**2 + flow[:,1:2]**2)
|
||||
flow_mag = (flow_mag - flow_mag.min()) / (flow_mag.max() - flow_mag.min()) + 1e-6
|
||||
texture = (texture - texture.min()) / (texture.max() - texture.min()) + 1e-6
|
||||
weight = flow_mag / texture
|
||||
weight /= torch.sum(weight)
|
||||
return torch.sum(in_tens*weight, dim=[2,3],keepdim=keepdim)
|
||||
|
||||
|
||||
|
||||
def m2w_spatial_average(in_tens, flow, keepdim=True):
|
||||
_,_,h,w = in_tens.shape
|
||||
flow = F.interpolate(flow, (h,w), align_corners=False, mode='bilinear')
|
||||
flow_mag = flow[:,0:1]**2 + flow[:,1:2]**2 # B,1,H,W
|
||||
flow_mag = flow_mag / torch.sum(flow_mag)
|
||||
return torch.sum(in_tens*flow_mag, dim=[2,3],keepdim=keepdim)
|
||||
|
||||
def upsample(in_tens, out_HW=(64,64)): # assumes scale factor is same for H and W
|
||||
in_H, in_W = in_tens.shape[2], in_tens.shape[3]
|
||||
return nn.Upsample(size=out_HW, mode='bilinear', align_corners=False)(in_tens)
|
||||
|
||||
# Learned perceptual metric
|
||||
class LPIPS(nn.Module):
|
||||
def __init__(self, pretrained=True, net='alex', version='0.1', lpips=True, spatial=False,
|
||||
pnet_rand=False, pnet_tune=False, use_dropout=True, model_path=None, eval_mode=True, verbose=False):
|
||||
# lpips - [True] means with linear calibration on top of base network
|
||||
# pretrained - [True] means load linear weights
|
||||
|
||||
super(LPIPS, self).__init__()
|
||||
if(verbose):
|
||||
print('Setting up [%s] perceptual loss: trunk [%s], v[%s], spatial [%s]'%
|
||||
('LPIPS' if lpips else 'baseline', net, version, 'on' if spatial else 'off'))
|
||||
|
||||
self.pnet_type = net
|
||||
self.pnet_tune = pnet_tune
|
||||
self.pnet_rand = pnet_rand
|
||||
self.spatial = spatial
|
||||
self.lpips = lpips # false means baseline of just averaging all layers
|
||||
self.version = version
|
||||
self.scaling_layer = ScalingLayer()
|
||||
|
||||
if(self.pnet_type in ['vgg','vgg16']):
|
||||
net_type = vgg16
|
||||
self.chns = [64,128,256,512,512]
|
||||
elif(self.pnet_type=='alex'):
|
||||
net_type = alexnet
|
||||
self.chns = [64,192,384,256,256]
|
||||
elif(self.pnet_type=='squeeze'):
|
||||
net_type = squeezenet
|
||||
self.chns = [64,128,256,384,384,512,512]
|
||||
self.L = len(self.chns)
|
||||
|
||||
self.net = net_type(pretrained=not self.pnet_rand, requires_grad=self.pnet_tune)
|
||||
|
||||
if(lpips):
|
||||
self.lin0 = NetLinLayer(self.chns[0], use_dropout=use_dropout)
|
||||
self.lin1 = NetLinLayer(self.chns[1], use_dropout=use_dropout)
|
||||
self.lin2 = NetLinLayer(self.chns[2], use_dropout=use_dropout)
|
||||
self.lin3 = NetLinLayer(self.chns[3], use_dropout=use_dropout)
|
||||
self.lin4 = NetLinLayer(self.chns[4], use_dropout=use_dropout)
|
||||
self.lins = [self.lin0,self.lin1,self.lin2,self.lin3,self.lin4]
|
||||
if(self.pnet_type=='squeeze'): # 7 layers for squeezenet
|
||||
self.lin5 = NetLinLayer(self.chns[5], use_dropout=use_dropout)
|
||||
self.lin6 = NetLinLayer(self.chns[6], use_dropout=use_dropout)
|
||||
self.lins+=[self.lin5,self.lin6]
|
||||
self.lins = nn.ModuleList(self.lins)
|
||||
|
||||
if(pretrained):
|
||||
if(model_path is None):
|
||||
import inspect
|
||||
import os
|
||||
model_path = os.path.abspath(os.path.join(inspect.getfile(self.__init__), '..', 'weights/v%s/%s.pth'%(version,net)))
|
||||
|
||||
if(verbose):
|
||||
print('Loading model from: %s'%model_path)
|
||||
self.load_state_dict(torch.load(model_path, map_location='cpu'), strict=False)
|
||||
|
||||
if(eval_mode):
|
||||
self.eval()
|
||||
|
||||
def forward(self, in0, in1, retPerLayer=False, normalize=False):
|
||||
if normalize: # turn on this flag if input is [0,1] so it can be adjusted to [-1, +1]
|
||||
in0 = 2 * in0 - 1
|
||||
in1 = 2 * in1 - 1
|
||||
|
||||
# v0.0 - original release had a bug, where input was not scaled
|
||||
in0_input, in1_input = (self.scaling_layer(in0), self.scaling_layer(in1)) if self.version=='0.1' else (in0, in1)
|
||||
outs0, outs1 = self.net.forward(in0_input), self.net.forward(in1_input)
|
||||
feats0, feats1, diffs = {}, {}, {}
|
||||
|
||||
for kk in range(self.L):
|
||||
feats0[kk], feats1[kk] = normalize_tensor(outs0[kk]), normalize_tensor(outs1[kk])
|
||||
diffs[kk] = (feats0[kk]-feats1[kk])**2
|
||||
|
||||
if(self.lpips):
|
||||
if(self.spatial):
|
||||
res = [upsample(self.lins[kk](diffs[kk]), out_HW=in0.shape[2:]) for kk in range(self.L)]
|
||||
else:
|
||||
res = [spatial_average(self.lins[kk](diffs[kk]), keepdim=True) for kk in range(self.L)]
|
||||
else:
|
||||
if(self.spatial):
|
||||
res = [upsample(diffs[kk].sum(dim=1,keepdim=True), out_HW=in0.shape[2:]) for kk in range(self.L)]
|
||||
else:
|
||||
res = [spatial_average(diffs[kk].sum(dim=1,keepdim=True), keepdim=True) for kk in range(self.L)]
|
||||
|
||||
# val = res[0]
|
||||
# for l in range(1,self.L):
|
||||
# val += res[l]
|
||||
# print(val)
|
||||
|
||||
# a = spatial_average(self.lins[kk](diffs[kk]), keepdim=True)
|
||||
# b = torch.max(self.lins[kk](feats0[kk]**2))
|
||||
# for kk in range(self.L):
|
||||
# a += spatial_average(self.lins[kk](diffs[kk]), keepdim=True)
|
||||
# b = torch.max(b,torch.max(self.lins[kk](feats0[kk]**2)))
|
||||
# a = a/self.L
|
||||
# from IPython import embed
|
||||
# embed()
|
||||
# return 10*torch.log10(b/a)
|
||||
|
||||
# if(retPerLayer):
|
||||
# return (val, res)
|
||||
# else:
|
||||
return torch.sum(torch.cat(res, 1), dim=(1,2,3), keepdims=False)
|
||||
|
||||
|
||||
class ScalingLayer(nn.Module):
|
||||
def __init__(self):
|
||||
super(ScalingLayer, self).__init__()
|
||||
self.register_buffer('shift', torch.Tensor([-.030,-.088,-.188])[None,:,None,None])
|
||||
self.register_buffer('scale', torch.Tensor([.458,.448,.450])[None,:,None,None])
|
||||
|
||||
def forward(self, inp):
|
||||
return (inp - self.shift) / self.scale
|
||||
|
||||
|
||||
class NetLinLayer(nn.Module):
|
||||
''' A single linear layer which does a 1x1 conv '''
|
||||
def __init__(self, chn_in, chn_out=1, use_dropout=False):
|
||||
super(NetLinLayer, self).__init__()
|
||||
|
||||
layers = [nn.Dropout(),] if(use_dropout) else []
|
||||
layers += [nn.Conv2d(chn_in, chn_out, 1, stride=1, padding=0, bias=False),]
|
||||
self.model = nn.Sequential(*layers)
|
||||
|
||||
def forward(self, x):
|
||||
return self.model(x)
|
||||
|
||||
class Dist2LogitLayer(nn.Module):
|
||||
''' takes 2 distances, puts through fc layers, spits out value between [0,1] (if use_sigmoid is True) '''
|
||||
def __init__(self, chn_mid=32, use_sigmoid=True):
|
||||
super(Dist2LogitLayer, self).__init__()
|
||||
|
||||
layers = [nn.Conv2d(5, chn_mid, 1, stride=1, padding=0, bias=True),]
|
||||
layers += [nn.LeakyReLU(0.2,True),]
|
||||
layers += [nn.Conv2d(chn_mid, chn_mid, 1, stride=1, padding=0, bias=True),]
|
||||
layers += [nn.LeakyReLU(0.2,True),]
|
||||
layers += [nn.Conv2d(chn_mid, 1, 1, stride=1, padding=0, bias=True),]
|
||||
if(use_sigmoid):
|
||||
layers += [nn.Sigmoid(),]
|
||||
self.model = nn.Sequential(*layers)
|
||||
|
||||
def forward(self,d0,d1,eps=0.1):
|
||||
return self.model.forward(torch.cat((d0,d1,d0-d1,d0/(d1+eps),d1/(d0+eps)),dim=1))
|
||||
|
||||
class BCERankingLoss(nn.Module):
|
||||
def __init__(self, chn_mid=32):
|
||||
super(BCERankingLoss, self).__init__()
|
||||
self.net = Dist2LogitLayer(chn_mid=chn_mid)
|
||||
# self.parameters = list(self.net.parameters())
|
||||
self.loss = torch.nn.BCELoss()
|
||||
|
||||
def forward(self, d0, d1, judge):
|
||||
per = (judge+1.)/2.
|
||||
self.logit = self.net.forward(d0,d1)
|
||||
return self.loss(self.logit, per)
|
||||
|
||||
# L2, DSSIM metrics
|
||||
class FakeNet(nn.Module):
|
||||
def __init__(self, use_gpu=True, colorspace='Lab'):
|
||||
super(FakeNet, self).__init__()
|
||||
self.use_gpu = use_gpu
|
||||
self.colorspace = colorspace
|
||||
|
||||
class L2(FakeNet):
|
||||
def forward(self, in0, in1, retPerLayer=None):
|
||||
assert(in0.size()[0]==1) # currently only supports batchSize 1
|
||||
|
||||
if(self.colorspace=='RGB'):
|
||||
(N,C,X,Y) = in0.size()
|
||||
value = torch.mean(torch.mean(torch.mean((in0-in1)**2,dim=1).view(N,1,X,Y),dim=2).view(N,1,1,Y),dim=3).view(N)
|
||||
return value
|
||||
elif(self.colorspace=='Lab'):
|
||||
value = l2(tensor2np(tensor2tensorlab(in0.data,to_norm=False)),
|
||||
tensor2np(tensor2tensorlab(in1.data,to_norm=False)), range=100.).astype('float')
|
||||
ret_var = Variable( torch.Tensor((value,) ) )
|
||||
if(self.use_gpu):
|
||||
ret_var = ret_var.cuda()
|
||||
return ret_var
|
||||
|
||||
class DSSIM(FakeNet):
|
||||
|
||||
def forward(self, in0, in1, retPerLayer=None):
|
||||
assert(in0.size()[0]==1) # currently only supports batchSize 1
|
||||
|
||||
if(self.colorspace=='RGB'):
|
||||
value = dssim(1.*tensor2im(in0.data), 1.*tensor2im(in1.data), range=255.).astype('float')
|
||||
elif(self.colorspace=='Lab'):
|
||||
value = dssim(tensor2np(tensor2tensorlab(in0.data,to_norm=False)),
|
||||
tensor2np(tensor2tensorlab(in1.data,to_norm=False)), range=100.).astype('float')
|
||||
ret_var = Variable( torch.Tensor((value,) ) )
|
||||
if(self.use_gpu):
|
||||
ret_var = ret_var.cuda()
|
||||
return ret_var
|
||||
|
||||
def print_network(net):
|
||||
num_params = 0
|
||||
for param in net.parameters():
|
||||
num_params += param.numel()
|
||||
print('Network',net)
|
||||
print('Total number of parameters: %d' % num_params)
|
||||
|
||||
|
||||
class FloLPIPS(LPIPS):
|
||||
def __init__(self, pretrained=True, net='alex', version='0.1', lpips=True, spatial=False, pnet_rand=False, pnet_tune=False, use_dropout=True, model_path=None, eval_mode=True, verbose=False):
|
||||
super(FloLPIPS, self).__init__(pretrained, net, version, lpips, spatial, pnet_rand, pnet_tune, use_dropout, model_path, eval_mode, verbose)
|
||||
|
||||
def forward(self, in0, in1, flow, retPerLayer=False, normalize=False):
|
||||
if normalize: # turn on this flag if input is [0,1] so it can be adjusted to [-1, +1]
|
||||
in0 = 2 * in0 - 1
|
||||
in1 = 2 * in1 - 1
|
||||
|
||||
in0_input, in1_input = (self.scaling_layer(in0), self.scaling_layer(in1)) if self.version=='0.1' else (in0, in1)
|
||||
outs0, outs1 = self.net.forward(in0_input), self.net.forward(in1_input)
|
||||
feats0, feats1, diffs = {}, {}, {}
|
||||
|
||||
for kk in range(self.L):
|
||||
feats0[kk], feats1[kk] = normalize_tensor(outs0[kk]), normalize_tensor(outs1[kk])
|
||||
diffs[kk] = (feats0[kk]-feats1[kk])**2
|
||||
|
||||
res = [mw_spatial_average(self.lins[kk](diffs[kk]), flow, keepdim=True) for kk in range(self.L)]
|
||||
|
||||
return torch.sum(torch.cat(res, 1), dim=(1,2,3), keepdims=False)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
class Flolpips(nn.Module):
|
||||
def __init__(self):
|
||||
super(Flolpips, self).__init__()
|
||||
self.loss_fn = FloLPIPS(net='alex',version='0.1')
|
||||
self.flownet = PWCNet()
|
||||
|
||||
@torch.no_grad()
|
||||
def forward(self, I0, I1, frame_dis, frame_ref):
|
||||
"""
|
||||
args:
|
||||
I0: first frame of the triplet, shape: [B, C, H, W]
|
||||
I1: third frame of the triplet, shape: [B, C, H, W]
|
||||
frame_dis: prediction of the intermediate frame, shape: [B, C, H, W]
|
||||
frame_ref: ground-truth of the intermediate frame, shape: [B, C, H, W]
|
||||
"""
|
||||
assert I0.size() == I1.size() == frame_dis.size() == frame_ref.size(), \
|
||||
"the 4 input tensors should have same size"
|
||||
|
||||
flow_ref = self.flownet(frame_ref, I0)
|
||||
flow_dis = self.flownet(frame_dis, I0)
|
||||
flow_diff = flow_ref - flow_dis
|
||||
flolpips_wrt_I0 = self.loss_fn.forward(frame_ref, frame_dis, flow_diff, normalize=True)
|
||||
|
||||
flow_ref = self.flownet(frame_ref, I1)
|
||||
flow_dis = self.flownet(frame_dis, I1)
|
||||
flow_diff = flow_ref - flow_dis
|
||||
flolpips_wrt_I1 = self.loss_fn.forward(frame_ref, frame_dis, flow_diff, normalize=True)
|
||||
|
||||
flolpips = (flolpips_wrt_I0 + flolpips_wrt_I1) / 2
|
||||
return flolpips
|
||||
@@ -0,0 +1,180 @@
|
||||
from collections import namedtuple
|
||||
import torch
|
||||
from torchvision import models as tv
|
||||
|
||||
class squeezenet(torch.nn.Module):
|
||||
def __init__(self, requires_grad=False, pretrained=True):
|
||||
super(squeezenet, self).__init__()
|
||||
pretrained_features = tv.squeezenet1_1(pretrained=pretrained).features
|
||||
self.slice1 = torch.nn.Sequential()
|
||||
self.slice2 = torch.nn.Sequential()
|
||||
self.slice3 = torch.nn.Sequential()
|
||||
self.slice4 = torch.nn.Sequential()
|
||||
self.slice5 = torch.nn.Sequential()
|
||||
self.slice6 = torch.nn.Sequential()
|
||||
self.slice7 = torch.nn.Sequential()
|
||||
self.N_slices = 7
|
||||
for x in range(2):
|
||||
self.slice1.add_module(str(x), pretrained_features[x])
|
||||
for x in range(2,5):
|
||||
self.slice2.add_module(str(x), pretrained_features[x])
|
||||
for x in range(5, 8):
|
||||
self.slice3.add_module(str(x), pretrained_features[x])
|
||||
for x in range(8, 10):
|
||||
self.slice4.add_module(str(x), pretrained_features[x])
|
||||
for x in range(10, 11):
|
||||
self.slice5.add_module(str(x), pretrained_features[x])
|
||||
for x in range(11, 12):
|
||||
self.slice6.add_module(str(x), pretrained_features[x])
|
||||
for x in range(12, 13):
|
||||
self.slice7.add_module(str(x), pretrained_features[x])
|
||||
if not requires_grad:
|
||||
for param in self.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
def forward(self, X):
|
||||
h = self.slice1(X)
|
||||
h_relu1 = h
|
||||
h = self.slice2(h)
|
||||
h_relu2 = h
|
||||
h = self.slice3(h)
|
||||
h_relu3 = h
|
||||
h = self.slice4(h)
|
||||
h_relu4 = h
|
||||
h = self.slice5(h)
|
||||
h_relu5 = h
|
||||
h = self.slice6(h)
|
||||
h_relu6 = h
|
||||
h = self.slice7(h)
|
||||
h_relu7 = h
|
||||
vgg_outputs = namedtuple("SqueezeOutputs", ['relu1','relu2','relu3','relu4','relu5','relu6','relu7'])
|
||||
out = vgg_outputs(h_relu1,h_relu2,h_relu3,h_relu4,h_relu5,h_relu6,h_relu7)
|
||||
|
||||
return out
|
||||
|
||||
|
||||
class alexnet(torch.nn.Module):
|
||||
def __init__(self, requires_grad=False, pretrained=True):
|
||||
super(alexnet, self).__init__()
|
||||
alexnet_pretrained_features = tv.alexnet(pretrained=pretrained).features
|
||||
self.slice1 = torch.nn.Sequential()
|
||||
self.slice2 = torch.nn.Sequential()
|
||||
self.slice3 = torch.nn.Sequential()
|
||||
self.slice4 = torch.nn.Sequential()
|
||||
self.slice5 = torch.nn.Sequential()
|
||||
self.N_slices = 5
|
||||
for x in range(2):
|
||||
self.slice1.add_module(str(x), alexnet_pretrained_features[x])
|
||||
for x in range(2, 5):
|
||||
self.slice2.add_module(str(x), alexnet_pretrained_features[x])
|
||||
for x in range(5, 8):
|
||||
self.slice3.add_module(str(x), alexnet_pretrained_features[x])
|
||||
for x in range(8, 10):
|
||||
self.slice4.add_module(str(x), alexnet_pretrained_features[x])
|
||||
for x in range(10, 12):
|
||||
self.slice5.add_module(str(x), alexnet_pretrained_features[x])
|
||||
if not requires_grad:
|
||||
for param in self.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
def forward(self, X):
|
||||
h = self.slice1(X)
|
||||
h_relu1 = h
|
||||
h = self.slice2(h)
|
||||
h_relu2 = h
|
||||
h = self.slice3(h)
|
||||
h_relu3 = h
|
||||
h = self.slice4(h)
|
||||
h_relu4 = h
|
||||
h = self.slice5(h)
|
||||
h_relu5 = h
|
||||
alexnet_outputs = namedtuple("AlexnetOutputs", ['relu1', 'relu2', 'relu3', 'relu4', 'relu5'])
|
||||
out = alexnet_outputs(h_relu1, h_relu2, h_relu3, h_relu4, h_relu5)
|
||||
|
||||
return out
|
||||
|
||||
class vgg16(torch.nn.Module):
|
||||
def __init__(self, requires_grad=False, pretrained=True):
|
||||
super(vgg16, self).__init__()
|
||||
vgg_pretrained_features = tv.vgg16(pretrained=pretrained).features
|
||||
self.slice1 = torch.nn.Sequential()
|
||||
self.slice2 = torch.nn.Sequential()
|
||||
self.slice3 = torch.nn.Sequential()
|
||||
self.slice4 = torch.nn.Sequential()
|
||||
self.slice5 = torch.nn.Sequential()
|
||||
self.N_slices = 5
|
||||
for x in range(4):
|
||||
self.slice1.add_module(str(x), vgg_pretrained_features[x])
|
||||
for x in range(4, 9):
|
||||
self.slice2.add_module(str(x), vgg_pretrained_features[x])
|
||||
for x in range(9, 16):
|
||||
self.slice3.add_module(str(x), vgg_pretrained_features[x])
|
||||
for x in range(16, 23):
|
||||
self.slice4.add_module(str(x), vgg_pretrained_features[x])
|
||||
for x in range(23, 30):
|
||||
self.slice5.add_module(str(x), vgg_pretrained_features[x])
|
||||
if not requires_grad:
|
||||
for param in self.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
def forward(self, X):
|
||||
h = self.slice1(X)
|
||||
h_relu1_2 = h
|
||||
h = self.slice2(h)
|
||||
h_relu2_2 = h
|
||||
h = self.slice3(h)
|
||||
h_relu3_3 = h
|
||||
h = self.slice4(h)
|
||||
h_relu4_3 = h
|
||||
h = self.slice5(h)
|
||||
h_relu5_3 = h
|
||||
vgg_outputs = namedtuple("VggOutputs", ['relu1_2', 'relu2_2', 'relu3_3', 'relu4_3', 'relu5_3'])
|
||||
out = vgg_outputs(h_relu1_2, h_relu2_2, h_relu3_3, h_relu4_3, h_relu5_3)
|
||||
|
||||
return out
|
||||
|
||||
|
||||
|
||||
class resnet(torch.nn.Module):
|
||||
def __init__(self, requires_grad=False, pretrained=True, num=18):
|
||||
super(resnet, self).__init__()
|
||||
if(num==18):
|
||||
self.net = tv.resnet18(pretrained=pretrained)
|
||||
elif(num==34):
|
||||
self.net = tv.resnet34(pretrained=pretrained)
|
||||
elif(num==50):
|
||||
self.net = tv.resnet50(pretrained=pretrained)
|
||||
elif(num==101):
|
||||
self.net = tv.resnet101(pretrained=pretrained)
|
||||
elif(num==152):
|
||||
self.net = tv.resnet152(pretrained=pretrained)
|
||||
self.N_slices = 5
|
||||
|
||||
self.conv1 = self.net.conv1
|
||||
self.bn1 = self.net.bn1
|
||||
self.relu = self.net.relu
|
||||
self.maxpool = self.net.maxpool
|
||||
self.layer1 = self.net.layer1
|
||||
self.layer2 = self.net.layer2
|
||||
self.layer3 = self.net.layer3
|
||||
self.layer4 = self.net.layer4
|
||||
|
||||
def forward(self, X):
|
||||
h = self.conv1(X)
|
||||
h = self.bn1(h)
|
||||
h = self.relu(h)
|
||||
h_relu1 = h
|
||||
h = self.maxpool(h)
|
||||
h = self.layer1(h)
|
||||
h_conv2 = h
|
||||
h = self.layer2(h)
|
||||
h_conv3 = h
|
||||
h = self.layer3(h)
|
||||
h_conv4 = h
|
||||
h = self.layer4(h)
|
||||
h_conv5 = h
|
||||
|
||||
outputs = namedtuple("Outputs", ['relu1','conv2','conv3','conv4','conv5'])
|
||||
out = outputs(h_relu1, h_conv2, h_conv3, h_conv4, h_conv5)
|
||||
|
||||
return out
|
||||
+344
@@ -0,0 +1,344 @@
|
||||
#!/usr/bin/env python
|
||||
|
||||
import torch
|
||||
|
||||
import getopt
|
||||
import math
|
||||
import numpy
|
||||
import os
|
||||
import PIL
|
||||
import PIL.Image
|
||||
import sys
|
||||
|
||||
# try:
|
||||
from .correlation import correlation # the custom cost volume layer
|
||||
# except:
|
||||
# sys.path.insert(0, './correlation'); import correlation # you should consider upgrading python
|
||||
# end
|
||||
|
||||
##########################################################
|
||||
|
||||
# assert(int(str('').join(torch.__version__.split('.')[0:2])) >= 13) # requires at least pytorch version 1.3.0
|
||||
|
||||
# torch.set_grad_enabled(False) # make sure to not compute gradients for computational performance
|
||||
|
||||
# torch.backends.cudnn.enabled = True # make sure to use cudnn for computational performance
|
||||
|
||||
# ##########################################################
|
||||
|
||||
# arguments_strModel = 'default' # 'default', or 'chairs-things'
|
||||
# arguments_strFirst = './images/first.png'
|
||||
# arguments_strSecond = './images/second.png'
|
||||
# arguments_strOut = './out.flo'
|
||||
|
||||
# for strOption, strArgument in getopt.getopt(sys.argv[1:], '', [ strParameter[2:] + '=' for strParameter in sys.argv[1::2] ])[0]:
|
||||
# if strOption == '--model' and strArgument != '': arguments_strModel = strArgument # which model to use
|
||||
# if strOption == '--first' and strArgument != '': arguments_strFirst = strArgument # path to the first frame
|
||||
# if strOption == '--second' and strArgument != '': arguments_strSecond = strArgument # path to the second frame
|
||||
# if strOption == '--out' and strArgument != '': arguments_strOut = strArgument # path to where the output should be stored
|
||||
# end
|
||||
|
||||
##########################################################
|
||||
|
||||
|
||||
|
||||
def backwarp(tenInput, tenFlow):
|
||||
backwarp_tenGrid = {}
|
||||
backwarp_tenPartial = {}
|
||||
if str(tenFlow.shape) not in backwarp_tenGrid:
|
||||
tenHor = torch.linspace(-1.0 + (1.0 / tenFlow.shape[3]), 1.0 - (1.0 / tenFlow.shape[3]), tenFlow.shape[3]).view(1, 1, 1, -1).expand(-1, -1, tenFlow.shape[2], -1)
|
||||
tenVer = torch.linspace(-1.0 + (1.0 / tenFlow.shape[2]), 1.0 - (1.0 / tenFlow.shape[2]), tenFlow.shape[2]).view(1, 1, -1, 1).expand(-1, -1, -1, tenFlow.shape[3])
|
||||
|
||||
backwarp_tenGrid[str(tenFlow.shape)] = torch.cat([ tenHor, tenVer ], 1).cuda()
|
||||
# end
|
||||
|
||||
if str(tenFlow.shape) not in backwarp_tenPartial:
|
||||
backwarp_tenPartial[str(tenFlow.shape)] = tenFlow.new_ones([ tenFlow.shape[0], 1, tenFlow.shape[2], tenFlow.shape[3] ])
|
||||
# end
|
||||
|
||||
tenFlow = torch.cat([ tenFlow[:, 0:1, :, :] / ((tenInput.shape[3] - 1.0) / 2.0), tenFlow[:, 1:2, :, :] / ((tenInput.shape[2] - 1.0) / 2.0) ], 1)
|
||||
tenInput = torch.cat([ tenInput, backwarp_tenPartial[str(tenFlow.shape)] ], 1)
|
||||
|
||||
tenOutput = torch.nn.functional.grid_sample(input=tenInput, grid=(backwarp_tenGrid[str(tenFlow.shape)] + tenFlow).permute(0, 2, 3, 1), mode='bilinear', padding_mode='zeros', align_corners=False)
|
||||
|
||||
tenMask = tenOutput[:, -1:, :, :]; tenMask[tenMask > 0.999] = 1.0; tenMask[tenMask < 1.0] = 0.0
|
||||
|
||||
return tenOutput[:, :-1, :, :] * tenMask
|
||||
# end
|
||||
|
||||
##########################################################
|
||||
|
||||
class Network(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super(Network, self).__init__()
|
||||
|
||||
class Extractor(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super(Extractor, self).__init__()
|
||||
|
||||
self.netOne = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=3, out_channels=16, kernel_size=3, stride=2, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=16, out_channels=16, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=16, out_channels=16, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netTwo = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=16, out_channels=32, kernel_size=3, stride=2, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=32, out_channels=32, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=32, out_channels=32, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netThr = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=32, out_channels=64, kernel_size=3, stride=2, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=64, out_channels=64, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=64, out_channels=64, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netFou = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=64, out_channels=96, kernel_size=3, stride=2, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=96, out_channels=96, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=96, out_channels=96, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netFiv = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=96, out_channels=128, kernel_size=3, stride=2, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=128, out_channels=128, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=128, out_channels=128, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netSix = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=128, out_channels=196, kernel_size=3, stride=2, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=196, out_channels=196, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=196, out_channels=196, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
# end
|
||||
|
||||
def forward(self, tenInput):
|
||||
tenOne = self.netOne(tenInput)
|
||||
tenTwo = self.netTwo(tenOne)
|
||||
tenThr = self.netThr(tenTwo)
|
||||
tenFou = self.netFou(tenThr)
|
||||
tenFiv = self.netFiv(tenFou)
|
||||
tenSix = self.netSix(tenFiv)
|
||||
|
||||
return [ tenOne, tenTwo, tenThr, tenFou, tenFiv, tenSix ]
|
||||
# end
|
||||
# end
|
||||
|
||||
class Decoder(torch.nn.Module):
|
||||
def __init__(self, intLevel):
|
||||
super(Decoder, self).__init__()
|
||||
|
||||
intPrevious = [ None, None, 81 + 32 + 2 + 2, 81 + 64 + 2 + 2, 81 + 96 + 2 + 2, 81 + 128 + 2 + 2, 81, None ][intLevel + 1]
|
||||
intCurrent = [ None, None, 81 + 32 + 2 + 2, 81 + 64 + 2 + 2, 81 + 96 + 2 + 2, 81 + 128 + 2 + 2, 81, None ][intLevel + 0]
|
||||
|
||||
if intLevel < 6: self.netUpflow = torch.nn.ConvTranspose2d(in_channels=2, out_channels=2, kernel_size=4, stride=2, padding=1)
|
||||
if intLevel < 6: self.netUpfeat = torch.nn.ConvTranspose2d(in_channels=intPrevious + 128 + 128 + 96 + 64 + 32, out_channels=2, kernel_size=4, stride=2, padding=1)
|
||||
if intLevel < 6: self.fltBackwarp = [ None, None, None, 5.0, 2.5, 1.25, 0.625, None ][intLevel + 1]
|
||||
|
||||
self.netOne = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=intCurrent, out_channels=128, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netTwo = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=intCurrent + 128, out_channels=128, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netThr = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=intCurrent + 128 + 128, out_channels=96, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netFou = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=intCurrent + 128 + 128 + 96, out_channels=64, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netFiv = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=intCurrent + 128 + 128 + 96 + 64, out_channels=32, kernel_size=3, stride=1, padding=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1)
|
||||
)
|
||||
|
||||
self.netSix = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=intCurrent + 128 + 128 + 96 + 64 + 32, out_channels=2, kernel_size=3, stride=1, padding=1)
|
||||
)
|
||||
# end
|
||||
|
||||
def forward(self, tenFirst, tenSecond, objPrevious):
|
||||
tenFlow = None
|
||||
tenFeat = None
|
||||
|
||||
if objPrevious is None:
|
||||
tenFlow = None
|
||||
tenFeat = None
|
||||
|
||||
tenVolume = torch.nn.functional.leaky_relu(input=correlation.FunctionCorrelation(tenFirst=tenFirst, tenSecond=tenSecond), negative_slope=0.1, inplace=False)
|
||||
|
||||
tenFeat = torch.cat([ tenVolume ], 1)
|
||||
|
||||
elif objPrevious is not None:
|
||||
tenFlow = self.netUpflow(objPrevious['tenFlow'])
|
||||
tenFeat = self.netUpfeat(objPrevious['tenFeat'])
|
||||
|
||||
tenVolume = torch.nn.functional.leaky_relu(input=correlation.FunctionCorrelation(tenFirst=tenFirst, tenSecond=backwarp(tenInput=tenSecond, tenFlow=tenFlow * self.fltBackwarp)), negative_slope=0.1, inplace=False)
|
||||
|
||||
tenFeat = torch.cat([ tenVolume, tenFirst, tenFlow, tenFeat ], 1)
|
||||
|
||||
# end
|
||||
|
||||
tenFeat = torch.cat([ self.netOne(tenFeat), tenFeat ], 1)
|
||||
tenFeat = torch.cat([ self.netTwo(tenFeat), tenFeat ], 1)
|
||||
tenFeat = torch.cat([ self.netThr(tenFeat), tenFeat ], 1)
|
||||
tenFeat = torch.cat([ self.netFou(tenFeat), tenFeat ], 1)
|
||||
tenFeat = torch.cat([ self.netFiv(tenFeat), tenFeat ], 1)
|
||||
|
||||
tenFlow = self.netSix(tenFeat)
|
||||
|
||||
return {
|
||||
'tenFlow': tenFlow,
|
||||
'tenFeat': tenFeat
|
||||
}
|
||||
# end
|
||||
# end
|
||||
|
||||
class Refiner(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super(Refiner, self).__init__()
|
||||
|
||||
self.netMain = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(in_channels=81 + 32 + 2 + 2 + 128 + 128 + 96 + 64 + 32, out_channels=128, kernel_size=3, stride=1, padding=1, dilation=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=128, out_channels=128, kernel_size=3, stride=1, padding=2, dilation=2),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=128, out_channels=128, kernel_size=3, stride=1, padding=4, dilation=4),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=128, out_channels=96, kernel_size=3, stride=1, padding=8, dilation=8),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=96, out_channels=64, kernel_size=3, stride=1, padding=16, dilation=16),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=64, out_channels=32, kernel_size=3, stride=1, padding=1, dilation=1),
|
||||
torch.nn.LeakyReLU(inplace=False, negative_slope=0.1),
|
||||
torch.nn.Conv2d(in_channels=32, out_channels=2, kernel_size=3, stride=1, padding=1, dilation=1)
|
||||
)
|
||||
# end
|
||||
|
||||
def forward(self, tenInput):
|
||||
return self.netMain(tenInput)
|
||||
# end
|
||||
# end
|
||||
|
||||
self.netExtractor = Extractor()
|
||||
|
||||
self.netTwo = Decoder(2)
|
||||
self.netThr = Decoder(3)
|
||||
self.netFou = Decoder(4)
|
||||
self.netFiv = Decoder(5)
|
||||
self.netSix = Decoder(6)
|
||||
|
||||
self.netRefiner = Refiner()
|
||||
|
||||
self.load_state_dict({ strKey.replace('module', 'net'): tenWeight for strKey, tenWeight in torch.hub.load_state_dict_from_url(url='http://content.sniklaus.com/github/pytorch-pwc/network-' + 'default' + '.pytorch').items() })
|
||||
# end
|
||||
|
||||
def forward(self, tenFirst, tenSecond):
|
||||
intWidth = tenFirst.shape[3]
|
||||
intHeight = tenFirst.shape[2]
|
||||
|
||||
intPreprocessedWidth = int(math.floor(math.ceil(intWidth / 64.0) * 64.0))
|
||||
intPreprocessedHeight = int(math.floor(math.ceil(intHeight / 64.0) * 64.0))
|
||||
|
||||
tenPreprocessedFirst = torch.nn.functional.interpolate(input=tenFirst, size=(intPreprocessedHeight, intPreprocessedWidth), mode='bilinear', align_corners=False)
|
||||
tenPreprocessedSecond = torch.nn.functional.interpolate(input=tenSecond, size=(intPreprocessedHeight, intPreprocessedWidth), mode='bilinear', align_corners=False)
|
||||
|
||||
tenFirst = self.netExtractor(tenPreprocessedFirst)
|
||||
tenSecond = self.netExtractor(tenPreprocessedSecond)
|
||||
|
||||
|
||||
objEstimate = self.netSix(tenFirst[-1], tenSecond[-1], None)
|
||||
objEstimate = self.netFiv(tenFirst[-2], tenSecond[-2], objEstimate)
|
||||
objEstimate = self.netFou(tenFirst[-3], tenSecond[-3], objEstimate)
|
||||
objEstimate = self.netThr(tenFirst[-4], tenSecond[-4], objEstimate)
|
||||
objEstimate = self.netTwo(tenFirst[-5], tenSecond[-5], objEstimate)
|
||||
|
||||
tenFlow = objEstimate['tenFlow'] + self.netRefiner(objEstimate['tenFeat'])
|
||||
tenFlow = 20.0 * torch.nn.functional.interpolate(input=tenFlow, size=(intHeight, intWidth), mode='bilinear', align_corners=False)
|
||||
tenFlow[:, 0, :, :] *= float(intWidth) / float(intPreprocessedWidth)
|
||||
tenFlow[:, 1, :, :] *= float(intHeight) / float(intPreprocessedHeight)
|
||||
|
||||
return tenFlow
|
||||
# end
|
||||
# end
|
||||
|
||||
netNetwork = None
|
||||
|
||||
##########################################################
|
||||
|
||||
def estimate(tenFirst, tenSecond):
|
||||
global netNetwork
|
||||
|
||||
if netNetwork is None:
|
||||
netNetwork = Network().cuda().eval()
|
||||
# end
|
||||
|
||||
assert(tenFirst.shape[1] == tenSecond.shape[1])
|
||||
assert(tenFirst.shape[2] == tenSecond.shape[2])
|
||||
|
||||
intWidth = tenFirst.shape[2]
|
||||
intHeight = tenFirst.shape[1]
|
||||
|
||||
assert(intWidth == 1024) # remember that there is no guarantee for correctness, comment this line out if you acknowledge this and want to continue
|
||||
assert(intHeight == 436) # remember that there is no guarantee for correctness, comment this line out if you acknowledge this and want to continue
|
||||
|
||||
tenPreprocessedFirst = tenFirst.cuda().view(1, 3, intHeight, intWidth)
|
||||
tenPreprocessedSecond = tenSecond.cuda().view(1, 3, intHeight, intWidth)
|
||||
|
||||
intPreprocessedWidth = int(math.floor(math.ceil(intWidth / 64.0) * 64.0))
|
||||
intPreprocessedHeight = int(math.floor(math.ceil(intHeight / 64.0) * 64.0))
|
||||
|
||||
tenPreprocessedFirst = torch.nn.functional.interpolate(input=tenPreprocessedFirst, size=(intPreprocessedHeight, intPreprocessedWidth), mode='bilinear', align_corners=False)
|
||||
tenPreprocessedSecond = torch.nn.functional.interpolate(input=tenPreprocessedSecond, size=(intPreprocessedHeight, intPreprocessedWidth), mode='bilinear', align_corners=False)
|
||||
|
||||
tenFlow = 20.0 * torch.nn.functional.interpolate(input=netNetwork(tenPreprocessedFirst, tenPreprocessedSecond), size=(intHeight, intWidth), mode='bilinear', align_corners=False)
|
||||
|
||||
tenFlow[:, 0, :, :] *= float(intWidth) / float(intPreprocessedWidth)
|
||||
tenFlow[:, 1, :, :] *= float(intHeight) / float(intPreprocessedHeight)
|
||||
|
||||
return tenFlow[0, :, :, :].cpu()
|
||||
# end
|
||||
|
||||
##########################################################
|
||||
|
||||
# if __name__ == '__main__':
|
||||
# tenFirst = torch.FloatTensor(numpy.ascontiguousarray(numpy.array(PIL.Image.open(arguments_strFirst))[:, :, ::-1].transpose(2, 0, 1).astype(numpy.float32) * (1.0 / 255.0)))
|
||||
# tenSecond = torch.FloatTensor(numpy.ascontiguousarray(numpy.array(PIL.Image.open(arguments_strSecond))[:, :, ::-1].transpose(2, 0, 1).astype(numpy.float32) * (1.0 / 255.0)))
|
||||
|
||||
# tenOutput = estimate(tenFirst, tenSecond)
|
||||
|
||||
# objOutput = open(arguments_strOut, 'wb')
|
||||
|
||||
# numpy.array([ 80, 73, 69, 72 ], numpy.uint8).tofile(objOutput)
|
||||
# numpy.array([ tenOutput.shape[2], tenOutput.shape[1] ], numpy.int32).tofile(objOutput)
|
||||
# numpy.array(tenOutput.numpy().transpose(1, 2, 0), numpy.float32).tofile(objOutput)
|
||||
|
||||
# objOutput.close()
|
||||
# end
|
||||
+95
@@ -0,0 +1,95 @@
|
||||
import numpy as np
|
||||
import cv2
|
||||
import torch
|
||||
|
||||
|
||||
def normalize_tensor(in_feat,eps=1e-10):
|
||||
norm_factor = torch.sqrt(torch.sum(in_feat**2,dim=1,keepdim=True))
|
||||
return in_feat/(norm_factor+eps)
|
||||
|
||||
def l2(p0, p1, range=255.):
|
||||
return .5*np.mean((p0 / range - p1 / range)**2)
|
||||
|
||||
def dssim(p0, p1, range=255.):
|
||||
from skimage.measure import compare_ssim
|
||||
return (1 - compare_ssim(p0, p1, data_range=range, multichannel=True)) / 2.
|
||||
|
||||
def tensor2im(image_tensor, imtype=np.uint8, cent=1., factor=255./2.):
|
||||
image_numpy = image_tensor[0].cpu().float().numpy()
|
||||
image_numpy = (np.transpose(image_numpy, (1, 2, 0)) + cent) * factor
|
||||
return image_numpy.astype(imtype)
|
||||
|
||||
def tensor2np(tensor_obj):
|
||||
# change dimension of a tensor object into a numpy array
|
||||
return tensor_obj[0].cpu().float().numpy().transpose((1,2,0))
|
||||
|
||||
def np2tensor(np_obj):
|
||||
# change dimenion of np array into tensor array
|
||||
return torch.Tensor(np_obj[:, :, :, np.newaxis].transpose((3, 2, 0, 1)))
|
||||
|
||||
def tensor2tensorlab(image_tensor,to_norm=True,mc_only=False):
|
||||
# image tensor to lab tensor
|
||||
from skimage import color
|
||||
|
||||
img = tensor2im(image_tensor)
|
||||
img_lab = color.rgb2lab(img)
|
||||
if(mc_only):
|
||||
img_lab[:,:,0] = img_lab[:,:,0]-50
|
||||
if(to_norm and not mc_only):
|
||||
img_lab[:,:,0] = img_lab[:,:,0]-50
|
||||
img_lab = img_lab/100.
|
||||
|
||||
return np2tensor(img_lab)
|
||||
|
||||
def read_frame_yuv2rgb(stream, width, height, iFrame, bit_depth, pix_fmt='420'):
|
||||
if pix_fmt == '420':
|
||||
multiplier = 1
|
||||
uv_factor = 2
|
||||
elif pix_fmt == '444':
|
||||
multiplier = 2
|
||||
uv_factor = 1
|
||||
else:
|
||||
print('Pixel format {} is not supported'.format(pix_fmt))
|
||||
return
|
||||
|
||||
if bit_depth == 8:
|
||||
datatype = np.uint8
|
||||
stream.seek(iFrame*1.5*width*height*multiplier)
|
||||
Y = np.fromfile(stream, dtype=datatype, count=width*height).reshape((height, width))
|
||||
|
||||
# read chroma samples and upsample since original is 4:2:0 sampling
|
||||
U = np.fromfile(stream, dtype=datatype, count=(width//uv_factor)*(height//uv_factor)).\
|
||||
reshape((height//uv_factor, width//uv_factor))
|
||||
V = np.fromfile(stream, dtype=datatype, count=(width//uv_factor)*(height//uv_factor)).\
|
||||
reshape((height//uv_factor, width//uv_factor))
|
||||
|
||||
else:
|
||||
datatype = np.uint16
|
||||
stream.seek(iFrame*3*width*height*multiplier)
|
||||
Y = np.fromfile(stream, dtype=datatype, count=width*height).reshape((height, width))
|
||||
|
||||
U = np.fromfile(stream, dtype=datatype, count=(width//uv_factor)*(height//uv_factor)).\
|
||||
reshape((height//uv_factor, width//uv_factor))
|
||||
V = np.fromfile(stream, dtype=datatype, count=(width//uv_factor)*(height//uv_factor)).\
|
||||
reshape((height//uv_factor, width//uv_factor))
|
||||
|
||||
if pix_fmt == '420':
|
||||
yuv = np.empty((height*3//2, width), dtype=datatype)
|
||||
yuv[0:height,:] = Y
|
||||
|
||||
yuv[height:height+height//4,:] = U.reshape(-1, width)
|
||||
yuv[height+height//4:,:] = V.reshape(-1, width)
|
||||
|
||||
if bit_depth != 8:
|
||||
yuv = (yuv/(2**bit_depth-1)*255).astype(np.uint8)
|
||||
|
||||
#convert to rgb
|
||||
rgb = cv2.cvtColor(yuv, cv2.COLOR_YUV2RGB_I420)
|
||||
|
||||
else:
|
||||
yvu = np.stack([Y,V,U],axis=2)
|
||||
if bit_depth != 8:
|
||||
yvu = (yvu/(2**bit_depth-1)*255).astype(np.uint8)
|
||||
rgb = cv2.cvtColor(yvu, cv2.COLOR_YCrCb2RGB)
|
||||
|
||||
return rgb
|
||||
@@ -0,0 +1,90 @@
|
||||
import torch
|
||||
import os
|
||||
import math
|
||||
import torch.nn.functional as F
|
||||
|
||||
# https://github.com/universome/fvd-comparison
|
||||
|
||||
|
||||
def load_i3d_pretrained(device=torch.device('cpu')):
|
||||
i3D_WEIGHTS_URL = "https://www.dropbox.com/s/ge9e5ujwgetktms/i3d_torchscript.pt"
|
||||
filepath = os.path.join(os.path.dirname(os.path.abspath(__file__)), 'i3d_torchscript.pt')
|
||||
print(filepath)
|
||||
if not os.path.exists(filepath):
|
||||
print(f"preparing for download {i3D_WEIGHTS_URL}, you can download it by yourself.")
|
||||
os.system(f"wget {i3D_WEIGHTS_URL} -O {filepath}")
|
||||
i3d = torch.jit.load(filepath).eval().to(device)
|
||||
i3d = torch.nn.DataParallel(i3d)
|
||||
return i3d
|
||||
|
||||
|
||||
def get_feats(videos, detector, device, bs=10):
|
||||
# videos : torch.tensor BCTHW [0, 1]
|
||||
detector_kwargs = dict(rescale=False, resize=False, return_features=True) # Return raw features before the softmax layer.
|
||||
feats = np.empty((0, 400))
|
||||
with torch.no_grad():
|
||||
for i in range((len(videos)-1)//bs + 1):
|
||||
feats = np.vstack([feats, detector(torch.stack([preprocess_single(video) for video in videos[i*bs:(i+1)*bs]]).to(device), **detector_kwargs).detach().cpu().numpy()])
|
||||
return feats
|
||||
|
||||
|
||||
def get_fvd_feats(videos, i3d, device, bs=10):
|
||||
# videos in [0, 1] as torch tensor BCTHW
|
||||
# videos = [preprocess_single(video) for video in videos]
|
||||
embeddings = get_feats(videos, i3d, device, bs)
|
||||
return embeddings
|
||||
|
||||
|
||||
def preprocess_single(video, resolution=224, sequence_length=None):
|
||||
# video: CTHW, [0, 1]
|
||||
c, t, h, w = video.shape
|
||||
|
||||
# temporal crop
|
||||
if sequence_length is not None:
|
||||
assert sequence_length <= t
|
||||
video = video[:, :sequence_length]
|
||||
|
||||
# scale shorter side to resolution
|
||||
scale = resolution / min(h, w)
|
||||
if h < w:
|
||||
target_size = (resolution, math.ceil(w * scale))
|
||||
else:
|
||||
target_size = (math.ceil(h * scale), resolution)
|
||||
video = F.interpolate(video, size=target_size, mode='bilinear', align_corners=False)
|
||||
|
||||
# center crop
|
||||
c, t, h, w = video.shape
|
||||
w_start = (w - resolution) // 2
|
||||
h_start = (h - resolution) // 2
|
||||
video = video[:, :, h_start:h_start + resolution, w_start:w_start + resolution]
|
||||
|
||||
# [0, 1] -> [-1, 1]
|
||||
video = (video - 0.5) * 2
|
||||
|
||||
return video.contiguous()
|
||||
|
||||
|
||||
"""
|
||||
Copy-pasted from https://github.com/cvpr2022-stylegan-v/stylegan-v/blob/main/src/metrics/frechet_video_distance.py
|
||||
"""
|
||||
from typing import Tuple
|
||||
from scipy.linalg import sqrtm
|
||||
import numpy as np
|
||||
|
||||
|
||||
def compute_stats(feats: np.ndarray) -> Tuple[np.ndarray, np.ndarray]:
|
||||
mu = feats.mean(axis=0) # [d]
|
||||
sigma = np.cov(feats, rowvar=False) # [d, d]
|
||||
return mu, sigma
|
||||
|
||||
|
||||
def frechet_distance(feats_fake: np.ndarray, feats_real: np.ndarray) -> float:
|
||||
mu_gen, sigma_gen = compute_stats(feats_fake)
|
||||
mu_real, sigma_real = compute_stats(feats_real)
|
||||
m = np.square(mu_gen - mu_real).sum()
|
||||
if feats_fake.shape[0]>1:
|
||||
s, _ = sqrtm(np.dot(sigma_gen, sigma_real), disp=False) # pylint: disable=no-member
|
||||
fid = np.real(m + np.trace(sigma_gen + sigma_real - s * 2))
|
||||
else:
|
||||
fid = np.real(m)
|
||||
return float(fid)
|
||||
+137
@@ -0,0 +1,137 @@
|
||||
import torch
|
||||
import os
|
||||
import math
|
||||
import torch.nn.functional as F
|
||||
import numpy as np
|
||||
import einops
|
||||
|
||||
def load_i3d_pretrained(device=torch.device('cpu')):
|
||||
i3D_WEIGHTS_URL = "https://onedrive.live.com/download?cid=78EEF3EB6AE7DBCB&resid=78EEF3EB6AE7DBCB%21199&authkey=AApKdFHPXzWLNyI"
|
||||
filepath = os.path.join(os.path.dirname(os.path.abspath(__file__)), 'i3d_pretrained_400.pt')
|
||||
print(filepath)
|
||||
if not os.path.exists(filepath):
|
||||
print(f"preparing for download {i3D_WEIGHTS_URL}, you can download it by yourself.")
|
||||
os.system(f"wget {i3D_WEIGHTS_URL} -O {filepath}")
|
||||
from .pytorch_i3d import InceptionI3d
|
||||
i3d = InceptionI3d(400, in_channels=3).eval().to(device)
|
||||
i3d.load_state_dict(torch.load(filepath, map_location=device))
|
||||
i3d = torch.nn.DataParallel(i3d)
|
||||
return i3d
|
||||
|
||||
def preprocess_single(video, resolution, sequence_length=None):
|
||||
# video: THWC, {0, ..., 255}
|
||||
video = video.permute(0, 3, 1, 2).float() / 255. # TCHW
|
||||
t, c, h, w = video.shape
|
||||
|
||||
# temporal crop
|
||||
if sequence_length is not None:
|
||||
assert sequence_length <= t
|
||||
video = video[:sequence_length]
|
||||
|
||||
# scale shorter side to resolution
|
||||
scale = resolution / min(h, w)
|
||||
if h < w:
|
||||
target_size = (resolution, math.ceil(w * scale))
|
||||
else:
|
||||
target_size = (math.ceil(h * scale), resolution)
|
||||
video = F.interpolate(video, size=target_size, mode='bilinear',
|
||||
align_corners=False)
|
||||
|
||||
# center crop
|
||||
t, c, h, w = video.shape
|
||||
w_start = (w - resolution) // 2
|
||||
h_start = (h - resolution) // 2
|
||||
video = video[:, :, h_start:h_start + resolution, w_start:w_start + resolution]
|
||||
video = video.permute(1, 0, 2, 3).contiguous() # CTHW
|
||||
|
||||
video -= 0.5
|
||||
|
||||
return video
|
||||
|
||||
def preprocess(videos, target_resolution=224):
|
||||
# we should tras videos in [0-1] [b c t h w] as th.float
|
||||
# -> videos in {0, ..., 255} [b t h w c] as np.uint8 array
|
||||
videos = einops.rearrange(videos, 'b c t h w -> b t h w c')
|
||||
videos = (videos*255).numpy().astype(np.uint8)
|
||||
|
||||
b, t, h, w, c = videos.shape
|
||||
videos = torch.from_numpy(videos)
|
||||
videos = torch.stack([preprocess_single(video, target_resolution) for video in videos])
|
||||
return videos * 2 # [-0.5, 0.5] -> [-1, 1]
|
||||
|
||||
def get_fvd_logits(videos, i3d, device, bs=10):
|
||||
videos = preprocess(videos)
|
||||
embeddings = get_logits(i3d, videos, device, bs=10)
|
||||
return embeddings
|
||||
|
||||
# https://github.com/tensorflow/gan/blob/de4b8da3853058ea380a6152bd3bd454013bf619/tensorflow_gan/python/eval/classifier_metrics.py#L161
|
||||
def _symmetric_matrix_square_root(mat, eps=1e-10):
|
||||
u, s, v = torch.svd(mat)
|
||||
si = torch.where(s < eps, s, torch.sqrt(s))
|
||||
return torch.matmul(torch.matmul(u, torch.diag(si)), v.t())
|
||||
|
||||
# https://github.com/tensorflow/gan/blob/de4b8da3853058ea380a6152bd3bd454013bf619/tensorflow_gan/python/eval/classifier_metrics.py#L400
|
||||
def trace_sqrt_product(sigma, sigma_v):
|
||||
sqrt_sigma = _symmetric_matrix_square_root(sigma)
|
||||
sqrt_a_sigmav_a = torch.matmul(sqrt_sigma, torch.matmul(sigma_v, sqrt_sigma))
|
||||
return torch.trace(_symmetric_matrix_square_root(sqrt_a_sigmav_a))
|
||||
|
||||
# https://discuss.pytorch.org/t/covariance-and-gradient-support/16217/2
|
||||
def cov(m, rowvar=False):
|
||||
'''Estimate a covariance matrix given data.
|
||||
|
||||
Covariance indicates the level to which two variables vary together.
|
||||
If we examine N-dimensional samples, `X = [x_1, x_2, ... x_N]^T`,
|
||||
then the covariance matrix element `C_{ij}` is the covariance of
|
||||
`x_i` and `x_j`. The element `C_{ii}` is the variance of `x_i`.
|
||||
|
||||
Args:
|
||||
m: A 1-D or 2-D array containing multiple variables and observations.
|
||||
Each row of `m` represents a variable, and each column a single
|
||||
observation of all those variables.
|
||||
rowvar: If `rowvar` is True, then each row represents a
|
||||
variable, with observations in the columns. Otherwise, the
|
||||
relationship is transposed: each column represents a variable,
|
||||
while the rows contain observations.
|
||||
|
||||
Returns:
|
||||
The covariance matrix of the variables.
|
||||
'''
|
||||
if m.dim() > 2:
|
||||
raise ValueError('m has more than 2 dimensions')
|
||||
if m.dim() < 2:
|
||||
m = m.view(1, -1)
|
||||
if not rowvar and m.size(0) != 1:
|
||||
m = m.t()
|
||||
|
||||
fact = 1.0 / (m.size(1) - 1) # unbiased estimate
|
||||
m -= torch.mean(m, dim=1, keepdim=True)
|
||||
mt = m.t() # if complex: mt = m.t().conj()
|
||||
return fact * m.matmul(mt).squeeze()
|
||||
|
||||
|
||||
def frechet_distance(x1, x2):
|
||||
x1 = x1.flatten(start_dim=1)
|
||||
x2 = x2.flatten(start_dim=1)
|
||||
m, m_w = x1.mean(dim=0), x2.mean(dim=0)
|
||||
sigma, sigma_w = cov(x1, rowvar=False), cov(x2, rowvar=False)
|
||||
mean = torch.sum((m - m_w) ** 2)
|
||||
if x1.shape[0]>1:
|
||||
sqrt_trace_component = trace_sqrt_product(sigma, sigma_w)
|
||||
trace = torch.trace(sigma + sigma_w) - 2.0 * sqrt_trace_component
|
||||
fd = trace + mean
|
||||
else:
|
||||
fd = np.real(mean)
|
||||
return float(fd)
|
||||
|
||||
|
||||
def get_logits(i3d, videos, device, bs=10):
|
||||
# assert videos.shape[0] % 16 == 0
|
||||
with torch.no_grad():
|
||||
logits = []
|
||||
for i in range(0, videos.shape[0], bs):
|
||||
batch = videos[i:i + bs].to(device)
|
||||
# logits.append(i3d.module.extract_features(batch)) # wrong
|
||||
logits.append(i3d(batch)) # right
|
||||
logits = torch.cat(logits, dim=0)
|
||||
return logits
|
||||
@@ -0,0 +1,322 @@
|
||||
# Original code from https://github.com/piergiaj/pytorch-i3d
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
import numpy as np
|
||||
|
||||
class MaxPool3dSamePadding(nn.MaxPool3d):
|
||||
|
||||
def compute_pad(self, dim, s):
|
||||
if s % self.stride[dim] == 0:
|
||||
return max(self.kernel_size[dim] - self.stride[dim], 0)
|
||||
else:
|
||||
return max(self.kernel_size[dim] - (s % self.stride[dim]), 0)
|
||||
|
||||
def forward(self, x):
|
||||
# compute 'same' padding
|
||||
(batch, channel, t, h, w) = x.size()
|
||||
out_t = np.ceil(float(t) / float(self.stride[0]))
|
||||
out_h = np.ceil(float(h) / float(self.stride[1]))
|
||||
out_w = np.ceil(float(w) / float(self.stride[2]))
|
||||
pad_t = self.compute_pad(0, t)
|
||||
pad_h = self.compute_pad(1, h)
|
||||
pad_w = self.compute_pad(2, w)
|
||||
|
||||
pad_t_f = pad_t // 2
|
||||
pad_t_b = pad_t - pad_t_f
|
||||
pad_h_f = pad_h // 2
|
||||
pad_h_b = pad_h - pad_h_f
|
||||
pad_w_f = pad_w // 2
|
||||
pad_w_b = pad_w - pad_w_f
|
||||
|
||||
pad = (pad_w_f, pad_w_b, pad_h_f, pad_h_b, pad_t_f, pad_t_b)
|
||||
x = F.pad(x, pad)
|
||||
return super(MaxPool3dSamePadding, self).forward(x)
|
||||
|
||||
|
||||
class Unit3D(nn.Module):
|
||||
|
||||
def __init__(self, in_channels,
|
||||
output_channels,
|
||||
kernel_shape=(1, 1, 1),
|
||||
stride=(1, 1, 1),
|
||||
padding=0,
|
||||
activation_fn=F.relu,
|
||||
use_batch_norm=True,
|
||||
use_bias=False,
|
||||
name='unit_3d'):
|
||||
|
||||
"""Initializes Unit3D module."""
|
||||
super(Unit3D, self).__init__()
|
||||
|
||||
self._output_channels = output_channels
|
||||
self._kernel_shape = kernel_shape
|
||||
self._stride = stride
|
||||
self._use_batch_norm = use_batch_norm
|
||||
self._activation_fn = activation_fn
|
||||
self._use_bias = use_bias
|
||||
self.name = name
|
||||
self.padding = padding
|
||||
|
||||
self.conv3d = nn.Conv3d(in_channels=in_channels,
|
||||
out_channels=self._output_channels,
|
||||
kernel_size=self._kernel_shape,
|
||||
stride=self._stride,
|
||||
padding=0, # we always want padding to be 0 here. We will dynamically pad based on input size in forward function
|
||||
bias=self._use_bias)
|
||||
|
||||
if self._use_batch_norm:
|
||||
self.bn = nn.BatchNorm3d(self._output_channels, eps=1e-5, momentum=0.001)
|
||||
|
||||
def compute_pad(self, dim, s):
|
||||
if s % self._stride[dim] == 0:
|
||||
return max(self._kernel_shape[dim] - self._stride[dim], 0)
|
||||
else:
|
||||
return max(self._kernel_shape[dim] - (s % self._stride[dim]), 0)
|
||||
|
||||
|
||||
def forward(self, x):
|
||||
# compute 'same' padding
|
||||
(batch, channel, t, h, w) = x.size()
|
||||
out_t = np.ceil(float(t) / float(self._stride[0]))
|
||||
out_h = np.ceil(float(h) / float(self._stride[1]))
|
||||
out_w = np.ceil(float(w) / float(self._stride[2]))
|
||||
pad_t = self.compute_pad(0, t)
|
||||
pad_h = self.compute_pad(1, h)
|
||||
pad_w = self.compute_pad(2, w)
|
||||
|
||||
pad_t_f = pad_t // 2
|
||||
pad_t_b = pad_t - pad_t_f
|
||||
pad_h_f = pad_h // 2
|
||||
pad_h_b = pad_h - pad_h_f
|
||||
pad_w_f = pad_w // 2
|
||||
pad_w_b = pad_w - pad_w_f
|
||||
|
||||
pad = (pad_w_f, pad_w_b, pad_h_f, pad_h_b, pad_t_f, pad_t_b)
|
||||
x = F.pad(x, pad)
|
||||
|
||||
x = self.conv3d(x)
|
||||
if self._use_batch_norm:
|
||||
x = self.bn(x)
|
||||
if self._activation_fn is not None:
|
||||
x = self._activation_fn(x)
|
||||
return x
|
||||
|
||||
|
||||
|
||||
class InceptionModule(nn.Module):
|
||||
def __init__(self, in_channels, out_channels, name):
|
||||
super(InceptionModule, self).__init__()
|
||||
|
||||
self.b0 = Unit3D(in_channels=in_channels, output_channels=out_channels[0], kernel_shape=[1, 1, 1], padding=0,
|
||||
name=name+'/Branch_0/Conv3d_0a_1x1')
|
||||
self.b1a = Unit3D(in_channels=in_channels, output_channels=out_channels[1], kernel_shape=[1, 1, 1], padding=0,
|
||||
name=name+'/Branch_1/Conv3d_0a_1x1')
|
||||
self.b1b = Unit3D(in_channels=out_channels[1], output_channels=out_channels[2], kernel_shape=[3, 3, 3],
|
||||
name=name+'/Branch_1/Conv3d_0b_3x3')
|
||||
self.b2a = Unit3D(in_channels=in_channels, output_channels=out_channels[3], kernel_shape=[1, 1, 1], padding=0,
|
||||
name=name+'/Branch_2/Conv3d_0a_1x1')
|
||||
self.b2b = Unit3D(in_channels=out_channels[3], output_channels=out_channels[4], kernel_shape=[3, 3, 3],
|
||||
name=name+'/Branch_2/Conv3d_0b_3x3')
|
||||
self.b3a = MaxPool3dSamePadding(kernel_size=[3, 3, 3],
|
||||
stride=(1, 1, 1), padding=0)
|
||||
self.b3b = Unit3D(in_channels=in_channels, output_channels=out_channels[5], kernel_shape=[1, 1, 1], padding=0,
|
||||
name=name+'/Branch_3/Conv3d_0b_1x1')
|
||||
self.name = name
|
||||
|
||||
def forward(self, x):
|
||||
b0 = self.b0(x)
|
||||
b1 = self.b1b(self.b1a(x))
|
||||
b2 = self.b2b(self.b2a(x))
|
||||
b3 = self.b3b(self.b3a(x))
|
||||
return torch.cat([b0,b1,b2,b3], dim=1)
|
||||
|
||||
|
||||
class InceptionI3d(nn.Module):
|
||||
"""Inception-v1 I3D architecture.
|
||||
The model is introduced in:
|
||||
Quo Vadis, Action Recognition? A New Model and the Kinetics Dataset
|
||||
Joao Carreira, Andrew Zisserman
|
||||
https://arxiv.org/pdf/1705.07750v1.pdf.
|
||||
See also the Inception architecture, introduced in:
|
||||
Going deeper with convolutions
|
||||
Christian Szegedy, Wei Liu, Yangqing Jia, Pierre Sermanet, Scott Reed,
|
||||
Dragomir Anguelov, Dumitru Erhan, Vincent Vanhoucke, Andrew Rabinovich.
|
||||
http://arxiv.org/pdf/1409.4842v1.pdf.
|
||||
"""
|
||||
|
||||
# Endpoints of the model in order. During construction, all the endpoints up
|
||||
# to a designated `final_endpoint` are returned in a dictionary as the
|
||||
# second return value.
|
||||
VALID_ENDPOINTS = (
|
||||
'Conv3d_1a_7x7',
|
||||
'MaxPool3d_2a_3x3',
|
||||
'Conv3d_2b_1x1',
|
||||
'Conv3d_2c_3x3',
|
||||
'MaxPool3d_3a_3x3',
|
||||
'Mixed_3b',
|
||||
'Mixed_3c',
|
||||
'MaxPool3d_4a_3x3',
|
||||
'Mixed_4b',
|
||||
'Mixed_4c',
|
||||
'Mixed_4d',
|
||||
'Mixed_4e',
|
||||
'Mixed_4f',
|
||||
'MaxPool3d_5a_2x2',
|
||||
'Mixed_5b',
|
||||
'Mixed_5c',
|
||||
'Logits',
|
||||
'Predictions',
|
||||
)
|
||||
|
||||
def __init__(self, num_classes=400, spatial_squeeze=True,
|
||||
final_endpoint='Logits', name='inception_i3d', in_channels=3, dropout_keep_prob=0.5):
|
||||
"""Initializes I3D model instance.
|
||||
Args:
|
||||
num_classes: The number of outputs in the logit layer (default 400, which
|
||||
matches the Kinetics dataset).
|
||||
spatial_squeeze: Whether to squeeze the spatial dimensions for the logits
|
||||
before returning (default True).
|
||||
final_endpoint: The model contains many possible endpoints.
|
||||
`final_endpoint` specifies the last endpoint for the model to be built
|
||||
up to. In addition to the output at `final_endpoint`, all the outputs
|
||||
at endpoints up to `final_endpoint` will also be returned, in a
|
||||
dictionary. `final_endpoint` must be one of
|
||||
InceptionI3d.VALID_ENDPOINTS (default 'Logits').
|
||||
name: A string (optional). The name of this module.
|
||||
Raises:
|
||||
ValueError: if `final_endpoint` is not recognized.
|
||||
"""
|
||||
|
||||
if final_endpoint not in self.VALID_ENDPOINTS:
|
||||
raise ValueError('Unknown final endpoint %s' % final_endpoint)
|
||||
|
||||
super(InceptionI3d, self).__init__()
|
||||
self._num_classes = num_classes
|
||||
self._spatial_squeeze = spatial_squeeze
|
||||
self._final_endpoint = final_endpoint
|
||||
self.logits = None
|
||||
|
||||
if self._final_endpoint not in self.VALID_ENDPOINTS:
|
||||
raise ValueError('Unknown final endpoint %s' % self._final_endpoint)
|
||||
|
||||
self.end_points = {}
|
||||
end_point = 'Conv3d_1a_7x7'
|
||||
self.end_points[end_point] = Unit3D(in_channels=in_channels, output_channels=64, kernel_shape=[7, 7, 7],
|
||||
stride=(2, 2, 2), padding=(3,3,3), name=name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'MaxPool3d_2a_3x3'
|
||||
self.end_points[end_point] = MaxPool3dSamePadding(kernel_size=[1, 3, 3], stride=(1, 2, 2),
|
||||
padding=0)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Conv3d_2b_1x1'
|
||||
self.end_points[end_point] = Unit3D(in_channels=64, output_channels=64, kernel_shape=[1, 1, 1], padding=0,
|
||||
name=name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Conv3d_2c_3x3'
|
||||
self.end_points[end_point] = Unit3D(in_channels=64, output_channels=192, kernel_shape=[3, 3, 3], padding=1,
|
||||
name=name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'MaxPool3d_3a_3x3'
|
||||
self.end_points[end_point] = MaxPool3dSamePadding(kernel_size=[1, 3, 3], stride=(1, 2, 2),
|
||||
padding=0)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_3b'
|
||||
self.end_points[end_point] = InceptionModule(192, [64,96,128,16,32,32], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_3c'
|
||||
self.end_points[end_point] = InceptionModule(256, [128,128,192,32,96,64], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'MaxPool3d_4a_3x3'
|
||||
self.end_points[end_point] = MaxPool3dSamePadding(kernel_size=[3, 3, 3], stride=(2, 2, 2),
|
||||
padding=0)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_4b'
|
||||
self.end_points[end_point] = InceptionModule(128+192+96+64, [192,96,208,16,48,64], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_4c'
|
||||
self.end_points[end_point] = InceptionModule(192+208+48+64, [160,112,224,24,64,64], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_4d'
|
||||
self.end_points[end_point] = InceptionModule(160+224+64+64, [128,128,256,24,64,64], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_4e'
|
||||
self.end_points[end_point] = InceptionModule(128+256+64+64, [112,144,288,32,64,64], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_4f'
|
||||
self.end_points[end_point] = InceptionModule(112+288+64+64, [256,160,320,32,128,128], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'MaxPool3d_5a_2x2'
|
||||
self.end_points[end_point] = MaxPool3dSamePadding(kernel_size=[2, 2, 2], stride=(2, 2, 2),
|
||||
padding=0)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_5b'
|
||||
self.end_points[end_point] = InceptionModule(256+320+128+128, [256,160,320,32,128,128], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Mixed_5c'
|
||||
self.end_points[end_point] = InceptionModule(256+320+128+128, [384,192,384,48,128,128], name+end_point)
|
||||
if self._final_endpoint == end_point: return
|
||||
|
||||
end_point = 'Logits'
|
||||
self.avg_pool = nn.AvgPool3d(kernel_size=[2, 7, 7],
|
||||
stride=(1, 1, 1))
|
||||
self.dropout = nn.Dropout(dropout_keep_prob)
|
||||
self.logits = Unit3D(in_channels=384+384+128+128, output_channels=self._num_classes,
|
||||
kernel_shape=[1, 1, 1],
|
||||
padding=0,
|
||||
activation_fn=None,
|
||||
use_batch_norm=False,
|
||||
use_bias=True,
|
||||
name='logits')
|
||||
|
||||
self.build()
|
||||
|
||||
|
||||
def replace_logits(self, num_classes):
|
||||
self._num_classes = num_classes
|
||||
self.logits = Unit3D(in_channels=384+384+128+128, output_channels=self._num_classes,
|
||||
kernel_shape=[1, 1, 1],
|
||||
padding=0,
|
||||
activation_fn=None,
|
||||
use_batch_norm=False,
|
||||
use_bias=True,
|
||||
name='logits')
|
||||
|
||||
|
||||
def build(self):
|
||||
for k in self.end_points.keys():
|
||||
self.add_module(k, self.end_points[k])
|
||||
|
||||
def forward(self, x):
|
||||
for end_point in self.VALID_ENDPOINTS:
|
||||
if end_point in self.end_points:
|
||||
x = self._modules[end_point](x) # use _modules to work with dataparallel
|
||||
|
||||
x = self.logits(self.dropout(self.avg_pool(x)))
|
||||
if self._spatial_squeeze:
|
||||
logits = x.squeeze(3).squeeze(3)
|
||||
logits = logits.mean(dim=2)
|
||||
# logits is batch X time X classes, which is what we want to work with
|
||||
return logits
|
||||
|
||||
|
||||
def extract_features(self, x):
|
||||
for end_point in self.VALID_ENDPOINTS:
|
||||
if end_point in self.end_points:
|
||||
x = self._modules[end_point](x)
|
||||
return self.avg_pool(x)
|
||||
@@ -0,0 +1,23 @@
|
||||
# clip_score cross modality
|
||||
python eval_clip_score.py \
|
||||
--real_path path/to/image \
|
||||
--generated_path path/to/text \
|
||||
--batch-size 50 \
|
||||
--device "cuda"
|
||||
|
||||
# clip_score within the same modality
|
||||
python eval_clip_score.py \
|
||||
--real_path path/to/textA \
|
||||
--generated_path path/to/textB \
|
||||
--real_flag txt \
|
||||
--generated_flag txt \
|
||||
--batch-size 50 \
|
||||
--device "cuda"
|
||||
|
||||
python eval_clip_score.py \
|
||||
--real_path path/to/imageA \
|
||||
--generated_path path/to/imageB \
|
||||
--real_flag img \
|
||||
--generated_flag img \
|
||||
--batch-size 50 \
|
||||
--device "cuda"
|
||||
@@ -0,0 +1,9 @@
|
||||
python eval_common_metric.py \
|
||||
--real_video_dir path/to/imageA\
|
||||
--generated_video_dir path/to/imageB \
|
||||
--batch_size 10 \
|
||||
--crop_size 64 \
|
||||
--num_frames 20 \
|
||||
--device 'cuda' \
|
||||
--metric 'fvd' \
|
||||
--fvd_method 'styleganv'
|
||||
@@ -0,0 +1,8 @@
|
||||
python eval_common_metric.py \
|
||||
--real_video_dir path/to/imageA\
|
||||
--generated_video_dir path/to/imageB \
|
||||
--batch_size 10 \
|
||||
--num_frames 20 \
|
||||
--crop_size 64 \
|
||||
--device 'cuda' \
|
||||
--metric 'lpips'
|
||||
@@ -0,0 +1,9 @@
|
||||
|
||||
python eval_common_metric.py \
|
||||
--real_video_dir /data/xiaogeng_liu/data/video1 \
|
||||
--generated_video_dir /data/xiaogeng_liu/data/video2 \
|
||||
--batch_size 10 \
|
||||
--num_frames 20 \
|
||||
--crop_size 64 \
|
||||
--device 'cuda' \
|
||||
--metric 'psnr'
|
||||
@@ -0,0 +1,8 @@
|
||||
python eval_common_metric.py \
|
||||
--real_video_dir /data/xiaogeng_liu/data/video1 \
|
||||
--generated_video_dir /data/xiaogeng_liu/data/video2 \
|
||||
--batch_size 10 \
|
||||
--num_frames 20 \
|
||||
--crop_size 64 \
|
||||
--device 'cuda' \
|
||||
--metric 'ssim'
|
||||
+4
@@ -0,0 +1,4 @@
|
||||
from .causal_vae import (
|
||||
CausalVAEModel, CausalVAEModelWrapper
|
||||
)
|
||||
from .ema_model import EMA
|
||||
@@ -0,0 +1,29 @@
|
||||
from .modeling_causalvae import CausalVAEModel
|
||||
|
||||
from einops import rearrange
|
||||
from torch import nn
|
||||
|
||||
class CausalVAEModelWrapper(nn.Module):
|
||||
def __init__(self, model_path, subfolder=None, cache_dir=None, use_ema=False, **kwargs):
|
||||
super(CausalVAEModelWrapper, self).__init__()
|
||||
# if os.path.exists(ckpt):
|
||||
# self.vae = CausalVAEModel.load_from_checkpoint(ckpt)
|
||||
self.vae = CausalVAEModel.from_pretrained(model_path, subfolder=subfolder, cache_dir=cache_dir, **kwargs)
|
||||
if use_ema:
|
||||
self.vae.init_from_ema(model_path)
|
||||
self.vae = self.vae.ema
|
||||
def encode(self, x): # b c t h w
|
||||
# x = self.vae.encode(x).sample()
|
||||
x = self.vae.encode(x).sample().mul_(0.18215)
|
||||
return x
|
||||
def decode(self, x):
|
||||
# x = self.vae.decode(x)
|
||||
x = self.vae.decode(x / 0.18215)
|
||||
x = rearrange(x, 'b c t h w -> b t c h w').contiguous()
|
||||
return x
|
||||
|
||||
def dtype(self):
|
||||
return self.vae.dtype
|
||||
#
|
||||
# def device(self):
|
||||
# return self.vae.device
|
||||
@@ -0,0 +1,628 @@
|
||||
try:
|
||||
import torch_npu
|
||||
from opensora.npu_config import npu_config
|
||||
except:
|
||||
torch_npu = None
|
||||
npu_config = None
|
||||
from ..modeling_videobase import VideoBaseAE
|
||||
from ..modules import Normalize
|
||||
from ..modules.ops import nonlinearity
|
||||
from typing import List, Tuple
|
||||
import torch.nn as nn
|
||||
|
||||
from ..utils.module_utils import resolve_str_to_obj, Module
|
||||
from ..utils.distrib_utils import DiagonalGaussianDistribution
|
||||
from ..utils.scheduler_utils import cosine_scheduler
|
||||
from ...utils.utils import custom_to_video
|
||||
|
||||
import torch
|
||||
from diffusers.configuration_utils import register_to_config
|
||||
from copy import deepcopy
|
||||
import os
|
||||
import glob
|
||||
|
||||
import numpy as np
|
||||
from ...eval.cal_psnr import calculate_psnr
|
||||
from decord import VideoReader, cpu
|
||||
from pytorchvideo.transforms import ShortSideScale
|
||||
from torchvision.io import read_video
|
||||
from torchvision.transforms import Lambda, Compose
|
||||
from torchvision.transforms._transforms_video import CenterCropVideo
|
||||
|
||||
class Encoder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
z_channels: int,
|
||||
hidden_size: int,
|
||||
hidden_size_mult: Tuple[int] = (1, 2, 4, 4),
|
||||
attn_resolutions: Tuple[int] = (16,),
|
||||
conv_in: Module = "Conv2d",
|
||||
conv_out: Module = "CasualConv3d",
|
||||
attention: Module = "AttnBlock",
|
||||
resnet_blocks: Tuple[Module] = (
|
||||
"ResnetBlock2D",
|
||||
"ResnetBlock2D",
|
||||
"ResnetBlock2D",
|
||||
"ResnetBlock3D",
|
||||
),
|
||||
spatial_downsample: Tuple[Module] = (
|
||||
"Downsample",
|
||||
"Downsample",
|
||||
"Downsample",
|
||||
"",
|
||||
),
|
||||
temporal_downsample: Tuple[Module] = ("", "", "TimeDownsampleRes2x", ""),
|
||||
mid_resnet: Module = "ResnetBlock3D",
|
||||
dropout: float = 0.0,
|
||||
resolution: int = 256,
|
||||
num_res_blocks: int = 2,
|
||||
double_z: bool = True,
|
||||
) -> None:
|
||||
super().__init__()
|
||||
assert len(resnet_blocks) == len(hidden_size_mult), print(
|
||||
hidden_size_mult, resnet_blocks
|
||||
)
|
||||
# ---- Config ----
|
||||
self.num_resolutions = len(hidden_size_mult)
|
||||
self.resolution = resolution
|
||||
self.num_res_blocks = num_res_blocks
|
||||
|
||||
# ---- In ----
|
||||
self.conv_in = resolve_str_to_obj(conv_in)(
|
||||
3, hidden_size, kernel_size=3, stride=1, padding=1
|
||||
)
|
||||
|
||||
# ---- Downsample ----
|
||||
curr_res = resolution
|
||||
in_ch_mult = (1,) + tuple(hidden_size_mult)
|
||||
self.in_ch_mult = in_ch_mult
|
||||
self.down = nn.ModuleList()
|
||||
for i_level in range(self.num_resolutions):
|
||||
block = nn.ModuleList()
|
||||
attn = nn.ModuleList()
|
||||
block_in = hidden_size * in_ch_mult[i_level]
|
||||
block_out = hidden_size * hidden_size_mult[i_level]
|
||||
for i_block in range(self.num_res_blocks):
|
||||
block.append(
|
||||
resolve_str_to_obj(resnet_blocks[i_level])(
|
||||
in_channels=block_in,
|
||||
out_channels=block_out,
|
||||
dropout=dropout,
|
||||
)
|
||||
)
|
||||
block_in = block_out
|
||||
if curr_res in attn_resolutions:
|
||||
attn.append(resolve_str_to_obj(attention)(block_in))
|
||||
down = nn.Module()
|
||||
down.block = block
|
||||
down.attn = attn
|
||||
if spatial_downsample[i_level]:
|
||||
down.downsample = resolve_str_to_obj(spatial_downsample[i_level])(
|
||||
block_in, block_in
|
||||
)
|
||||
curr_res = curr_res // 2
|
||||
if temporal_downsample[i_level]:
|
||||
down.time_downsample = resolve_str_to_obj(temporal_downsample[i_level])(
|
||||
block_in, block_in
|
||||
)
|
||||
self.down.append(down)
|
||||
|
||||
# ---- Mid ----
|
||||
self.mid = nn.Module()
|
||||
self.mid.block_1 = resolve_str_to_obj(mid_resnet)(
|
||||
in_channels=block_in,
|
||||
out_channels=block_in,
|
||||
dropout=dropout,
|
||||
)
|
||||
self.mid.attn_1 = resolve_str_to_obj(attention)(block_in)
|
||||
self.mid.block_2 = resolve_str_to_obj(mid_resnet)(
|
||||
in_channels=block_in,
|
||||
out_channels=block_in,
|
||||
dropout=dropout,
|
||||
)
|
||||
# ---- Out ----
|
||||
self.norm_out = Normalize(block_in)
|
||||
self.conv_out = resolve_str_to_obj(conv_out)(
|
||||
block_in,
|
||||
2 * z_channels if double_z else z_channels,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1,
|
||||
)
|
||||
|
||||
def forward(self, x):
|
||||
hs = [self.conv_in(x)]
|
||||
for i_level in range(self.num_resolutions):
|
||||
for i_block in range(self.num_res_blocks):
|
||||
h = self.down[i_level].block[i_block](hs[-1])
|
||||
if len(self.down[i_level].attn) > 0:
|
||||
h = self.down[i_level].attn[i_block](h)
|
||||
hs.append(h)
|
||||
if hasattr(self.down[i_level], "downsample"):
|
||||
hs.append(self.down[i_level].downsample(hs[-1]))
|
||||
if hasattr(self.down[i_level], "time_downsample"):
|
||||
hs_down = self.down[i_level].time_downsample(hs[-1])
|
||||
hs.append(hs_down)
|
||||
|
||||
h = self.mid.block_1(h)
|
||||
h = self.mid.attn_1(h)
|
||||
h = self.mid.block_2(h)
|
||||
|
||||
if npu_config is None:
|
||||
h = self.norm_out(h)
|
||||
else:
|
||||
h = npu_config.run_group_norm(self.norm_out, h)
|
||||
h = nonlinearity(h)
|
||||
h = self.conv_out(h)
|
||||
return h
|
||||
|
||||
|
||||
class Decoder(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
z_channels: int,
|
||||
hidden_size: int,
|
||||
hidden_size_mult: Tuple[int] = (1, 2, 4, 4),
|
||||
attn_resolutions: Tuple[int] = (16,),
|
||||
conv_in: Module = "Conv2d",
|
||||
conv_out: Module = "CasualConv3d",
|
||||
attention: Module = "AttnBlock",
|
||||
resnet_blocks: Tuple[Module] = (
|
||||
"ResnetBlock3D",
|
||||
"ResnetBlock3D",
|
||||
"ResnetBlock3D",
|
||||
"ResnetBlock3D",
|
||||
),
|
||||
spatial_upsample: Tuple[Module] = (
|
||||
"",
|
||||
"SpatialUpsample2x",
|
||||
"SpatialUpsample2x",
|
||||
"SpatialUpsample2x",
|
||||
),
|
||||
temporal_upsample: Tuple[Module] = ("", "", "", "TimeUpsampleRes2x"),
|
||||
mid_resnet: Module = "ResnetBlock3D",
|
||||
dropout: float = 0.0,
|
||||
resolution: int = 256,
|
||||
num_res_blocks: int = 2,
|
||||
):
|
||||
super().__init__()
|
||||
# ---- Config ----
|
||||
self.num_resolutions = len(hidden_size_mult)
|
||||
self.resolution = resolution
|
||||
self.num_res_blocks = num_res_blocks
|
||||
|
||||
# ---- In ----
|
||||
block_in = hidden_size * hidden_size_mult[self.num_resolutions - 1]
|
||||
curr_res = resolution // 2 ** (self.num_resolutions - 1)
|
||||
self.conv_in = resolve_str_to_obj(conv_in)(
|
||||
z_channels, block_in, kernel_size=3, padding=1
|
||||
)
|
||||
|
||||
# ---- Mid ----
|
||||
self.mid = nn.Module()
|
||||
self.mid.block_1 = resolve_str_to_obj(mid_resnet)(
|
||||
in_channels=block_in,
|
||||
out_channels=block_in,
|
||||
dropout=dropout,
|
||||
)
|
||||
self.mid.attn_1 = resolve_str_to_obj(attention)(block_in)
|
||||
self.mid.block_2 = resolve_str_to_obj(mid_resnet)(
|
||||
in_channels=block_in,
|
||||
out_channels=block_in,
|
||||
dropout=dropout,
|
||||
)
|
||||
|
||||
# ---- Upsample ----
|
||||
self.up = nn.ModuleList()
|
||||
for i_level in reversed(range(self.num_resolutions)):
|
||||
block = nn.ModuleList()
|
||||
attn = nn.ModuleList()
|
||||
block_out = hidden_size * hidden_size_mult[i_level]
|
||||
for i_block in range(self.num_res_blocks + 1):
|
||||
block.append(
|
||||
resolve_str_to_obj(resnet_blocks[i_level])(
|
||||
in_channels=block_in,
|
||||
out_channels=block_out,
|
||||
dropout=dropout,
|
||||
)
|
||||
)
|
||||
block_in = block_out
|
||||
if curr_res in attn_resolutions:
|
||||
attn.append(resolve_str_to_obj(attention)(block_in))
|
||||
up = nn.Module()
|
||||
up.block = block
|
||||
up.attn = attn
|
||||
if spatial_upsample[i_level]:
|
||||
up.upsample = resolve_str_to_obj(spatial_upsample[i_level])(
|
||||
block_in, block_in
|
||||
)
|
||||
curr_res = curr_res * 2
|
||||
if temporal_upsample[i_level]:
|
||||
up.time_upsample = resolve_str_to_obj(temporal_upsample[i_level])(
|
||||
block_in, block_in
|
||||
)
|
||||
self.up.insert(0, up)
|
||||
|
||||
# ---- Out ----
|
||||
self.norm_out = Normalize(block_in)
|
||||
self.conv_out = resolve_str_to_obj(conv_out)(
|
||||
block_in, 3, kernel_size=3, padding=1
|
||||
)
|
||||
|
||||
def forward(self, z):
|
||||
h = self.conv_in(z)
|
||||
h = self.mid.block_1(h)
|
||||
h = self.mid.attn_1(h)
|
||||
h = self.mid.block_2(h)
|
||||
|
||||
for i_level in reversed(range(self.num_resolutions)):
|
||||
for i_block in range(self.num_res_blocks + 1):
|
||||
h = self.up[i_level].block[i_block](h)
|
||||
if len(self.up[i_level].attn) > 0:
|
||||
h = self.up[i_level].attn[i_block](h)
|
||||
if hasattr(self.up[i_level], "upsample"):
|
||||
h = self.up[i_level].upsample(h)
|
||||
if hasattr(self.up[i_level], "time_upsample"):
|
||||
h = self.up[i_level].time_upsample(h)
|
||||
if npu_config is None:
|
||||
h = self.norm_out(h)
|
||||
else:
|
||||
h = npu_config.run_group_norm(self.norm_out, h)
|
||||
h = nonlinearity(h)
|
||||
if npu_config is None:
|
||||
h = self.conv_out(h)
|
||||
else:
|
||||
h_dtype = h.dtype
|
||||
h = npu_config.run_conv3d(self.conv_out, h, h_dtype)
|
||||
return h
|
||||
|
||||
|
||||
class CausalVAEModel(VideoBaseAE):
|
||||
|
||||
@register_to_config
|
||||
def __init__(
|
||||
self,
|
||||
hidden_size: int = 128,
|
||||
z_channels: int = 4,
|
||||
hidden_size_mult: Tuple[int] = (1, 2, 4, 4),
|
||||
attn_resolutions: Tuple[int] = [],
|
||||
dropout: float = 0.0,
|
||||
resolution: int = 256,
|
||||
double_z: bool = True,
|
||||
embed_dim: int = 4,
|
||||
num_res_blocks: int = 2,
|
||||
q_conv: str = "CausalConv3d",
|
||||
encoder_conv_in: Module = "CausalConv3d",
|
||||
encoder_conv_out: Module = "CausalConv3d",
|
||||
encoder_attention: Module = "AttnBlock3D",
|
||||
encoder_resnet_blocks: Tuple[Module] = (
|
||||
"ResnetBlock3D",
|
||||
"ResnetBlock3D",
|
||||
"ResnetBlock3D",
|
||||
"ResnetBlock3D",
|
||||
),
|
||||
encoder_spatial_downsample: Tuple[Module] = (
|
||||
"SpatialDownsample2x",
|
||||
"SpatialDownsample2x",
|
||||
"SpatialDownsample2x",
|
||||
"",
|
||||
),
|
||||
encoder_temporal_downsample: Tuple[Module] = (
|
||||
"",
|
||||
"TimeDownsample2x",
|
||||
"TimeDownsample2x",
|
||||
"",
|
||||
),
|
||||
encoder_mid_resnet: Module = "ResnetBlock3D",
|
||||
decoder_conv_in: Module = "CausalConv3d",
|
||||
decoder_conv_out: Module = "CausalConv3d",
|
||||
decoder_attention: Module = "AttnBlock3D",
|
||||
decoder_resnet_blocks: Tuple[Module] = (
|
||||
"ResnetBlock3D",
|
||||
"ResnetBlock3D",
|
||||
"ResnetBlock3D",
|
||||
"ResnetBlock3D",
|
||||
),
|
||||
decoder_spatial_upsample: Tuple[Module] = (
|
||||
"",
|
||||
"SpatialUpsample2x",
|
||||
"SpatialUpsample2x",
|
||||
"SpatialUpsample2x",
|
||||
),
|
||||
decoder_temporal_upsample: Tuple[Module] = ("", "", "TimeUpsample2x", "TimeUpsample2x"),
|
||||
decoder_mid_resnet: Module = "ResnetBlock3D",
|
||||
use_quant_layer: bool = True
|
||||
) -> None:
|
||||
super().__init__()
|
||||
|
||||
|
||||
self.tile_sample_min_size = 256
|
||||
self.tile_sample_min_size_t = 33
|
||||
self.tile_latent_min_size = int(self.tile_sample_min_size / (2 ** (len(hidden_size_mult) - 1)))
|
||||
|
||||
# t_down_ratio = [i for i in encoder_temporal_downsample if len(i) > 0]
|
||||
# self.tile_latent_min_size_t = int((self.tile_sample_min_size_t-1) / (2 ** len(t_down_ratio))) + 1
|
||||
self.tile_latent_min_size_t = 16
|
||||
self.tile_overlap_factor = 0.125
|
||||
self.use_tiling = False
|
||||
|
||||
self.use_quant_layer = use_quant_layer
|
||||
|
||||
self.encoder = Encoder(
|
||||
z_channels=z_channels,
|
||||
hidden_size=hidden_size,
|
||||
hidden_size_mult=hidden_size_mult,
|
||||
attn_resolutions=attn_resolutions,
|
||||
conv_in=encoder_conv_in,
|
||||
conv_out=encoder_conv_out,
|
||||
attention=encoder_attention,
|
||||
resnet_blocks=encoder_resnet_blocks,
|
||||
spatial_downsample=encoder_spatial_downsample,
|
||||
temporal_downsample=encoder_temporal_downsample,
|
||||
mid_resnet=encoder_mid_resnet,
|
||||
dropout=dropout,
|
||||
resolution=resolution,
|
||||
num_res_blocks=num_res_blocks,
|
||||
double_z=double_z,
|
||||
)
|
||||
|
||||
self.decoder = Decoder(
|
||||
z_channels=z_channels,
|
||||
hidden_size=hidden_size,
|
||||
hidden_size_mult=hidden_size_mult,
|
||||
attn_resolutions=attn_resolutions,
|
||||
conv_in=decoder_conv_in,
|
||||
conv_out=decoder_conv_out,
|
||||
attention=decoder_attention,
|
||||
resnet_blocks=decoder_resnet_blocks,
|
||||
spatial_upsample=decoder_spatial_upsample,
|
||||
temporal_upsample=decoder_temporal_upsample,
|
||||
mid_resnet=decoder_mid_resnet,
|
||||
dropout=dropout,
|
||||
resolution=resolution,
|
||||
num_res_blocks=num_res_blocks,
|
||||
)
|
||||
if self.use_quant_layer:
|
||||
quant_conv_cls = resolve_str_to_obj(q_conv)
|
||||
self.quant_conv = quant_conv_cls(2 * z_channels, 2 * embed_dim, 1)
|
||||
self.post_quant_conv = quant_conv_cls(embed_dim, z_channels, 1)
|
||||
|
||||
def get_encoder(self):
|
||||
if self.use_quant_layer:
|
||||
return [self.quant_conv, self.encoder]
|
||||
return [self.encoder]
|
||||
|
||||
def get_decoder(self):
|
||||
if self.use_quant_layer:
|
||||
return [self.post_quant_conv, self.decoder]
|
||||
return [self.decoder]
|
||||
|
||||
def encode(self, x):
|
||||
if self.use_tiling and (
|
||||
x.shape[-1] > self.tile_sample_min_size
|
||||
or x.shape[-2] > self.tile_sample_min_size
|
||||
or x.shape[-3] > self.tile_sample_min_size_t
|
||||
):
|
||||
return self.tiled_encode(x)
|
||||
h = self.encoder(x)
|
||||
if self.use_quant_layer:
|
||||
h = self.quant_conv(h)
|
||||
posterior = DiagonalGaussianDistribution(h)
|
||||
return posterior
|
||||
|
||||
def decode(self, z):
|
||||
if self.use_tiling and (
|
||||
z.shape[-1] > self.tile_latent_min_size
|
||||
or z.shape[-2] > self.tile_latent_min_size
|
||||
or z.shape[-3] > self.tile_latent_min_size_t
|
||||
):
|
||||
return self.tiled_decode(z)
|
||||
if self.use_quant_layer:
|
||||
z = self.post_quant_conv(z)
|
||||
dec = self.decoder(z)
|
||||
return dec
|
||||
|
||||
def forward(self, input, sample_posterior=True):
|
||||
posterior = self.encode(input)
|
||||
if sample_posterior:
|
||||
z = posterior.sample()
|
||||
else:
|
||||
z = posterior.mode()
|
||||
dec = self.decode(z)
|
||||
return dec, posterior
|
||||
|
||||
def on_train_start(self):
|
||||
self.ema = deepcopy(self) if self.save_ema==True else None
|
||||
|
||||
def get_last_layer(self):
|
||||
if hasattr(self.decoder.conv_out, "conv"):
|
||||
return self.decoder.conv_out.conv.weight
|
||||
else:
|
||||
return self.decoder.conv_out.weight
|
||||
|
||||
def blend_v(
|
||||
self, a: torch.Tensor, b: torch.Tensor, blend_extent: int
|
||||
) -> torch.Tensor:
|
||||
blend_extent = min(a.shape[3], b.shape[3], blend_extent)
|
||||
for y in range(blend_extent):
|
||||
b[:, :, :, y, :] = a[:, :, :, -blend_extent + y, :] * (
|
||||
1 - y / blend_extent
|
||||
) + b[:, :, :, y, :] * (y / blend_extent)
|
||||
return b
|
||||
|
||||
def blend_h(
|
||||
self, a: torch.Tensor, b: torch.Tensor, blend_extent: int
|
||||
) -> torch.Tensor:
|
||||
blend_extent = min(a.shape[4], b.shape[4], blend_extent)
|
||||
for x in range(blend_extent):
|
||||
b[:, :, :, :, x] = a[:, :, :, :, -blend_extent + x] * (
|
||||
1 - x / blend_extent
|
||||
) + b[:, :, :, :, x] * (x / blend_extent)
|
||||
return b
|
||||
|
||||
def tiled_encode(self, x):
|
||||
t = x.shape[2]
|
||||
t_chunk_idx = [i for i in range(0, t, self.tile_sample_min_size_t-1)]
|
||||
if len(t_chunk_idx) == 1 and t_chunk_idx[0] == 0:
|
||||
t_chunk_start_end = [[0, t]]
|
||||
else:
|
||||
t_chunk_start_end = [[t_chunk_idx[i], t_chunk_idx[i+1]+1] for i in range(len(t_chunk_idx)-1)]
|
||||
if t_chunk_start_end[-1][-1] > t:
|
||||
t_chunk_start_end[-1][-1] = t
|
||||
elif t_chunk_start_end[-1][-1] < t:
|
||||
last_start_end = [t_chunk_idx[-1], t]
|
||||
t_chunk_start_end.append(last_start_end)
|
||||
moments = []
|
||||
for idx, (start, end) in enumerate(t_chunk_start_end):
|
||||
chunk_x = x[:, :, start: end]
|
||||
if idx != 0:
|
||||
moment = self.tiled_encode2d(chunk_x, return_moments=True)[:, :, 1:]
|
||||
else:
|
||||
moment = self.tiled_encode2d(chunk_x, return_moments=True)
|
||||
moments.append(moment)
|
||||
moments = torch.cat(moments, dim=2)
|
||||
posterior = DiagonalGaussianDistribution(moments)
|
||||
return posterior
|
||||
|
||||
def tiled_decode(self, x):
|
||||
t = x.shape[2]
|
||||
t_chunk_idx = [i for i in range(0, t, self.tile_latent_min_size_t-1)]
|
||||
if len(t_chunk_idx) == 1 and t_chunk_idx[0] == 0:
|
||||
t_chunk_start_end = [[0, t]]
|
||||
else:
|
||||
t_chunk_start_end = [[t_chunk_idx[i], t_chunk_idx[i+1]+1] for i in range(len(t_chunk_idx)-1)]
|
||||
if t_chunk_start_end[-1][-1] > t:
|
||||
t_chunk_start_end[-1][-1] = t
|
||||
elif t_chunk_start_end[-1][-1] < t:
|
||||
last_start_end = [t_chunk_idx[-1], t]
|
||||
t_chunk_start_end.append(last_start_end)
|
||||
dec_ = []
|
||||
for idx, (start, end) in enumerate(t_chunk_start_end):
|
||||
chunk_x = x[:, :, start: end]
|
||||
if idx != 0:
|
||||
dec = self.tiled_decode2d(chunk_x)[:, :, 1:]
|
||||
else:
|
||||
dec = self.tiled_decode2d(chunk_x)
|
||||
dec_.append(dec)
|
||||
dec_ = torch.cat(dec_, dim=2)
|
||||
return dec_
|
||||
|
||||
def tiled_encode2d(self, x, return_moments=False):
|
||||
overlap_size = int(self.tile_sample_min_size * (1 - self.tile_overlap_factor))
|
||||
blend_extent = int(self.tile_latent_min_size * self.tile_overlap_factor)
|
||||
row_limit = self.tile_latent_min_size - blend_extent
|
||||
|
||||
# Split the image into 512x512 tiles and encode them separately.
|
||||
rows = []
|
||||
for i in range(0, x.shape[3], overlap_size):
|
||||
row = []
|
||||
for j in range(0, x.shape[4], overlap_size):
|
||||
tile = x[
|
||||
:,
|
||||
:,
|
||||
:,
|
||||
i : i + self.tile_sample_min_size,
|
||||
j : j + self.tile_sample_min_size,
|
||||
]
|
||||
tile = self.encoder(tile)
|
||||
if self.use_quant_layer:
|
||||
tile = self.quant_conv(tile)
|
||||
row.append(tile)
|
||||
rows.append(row)
|
||||
result_rows = []
|
||||
for i, row in enumerate(rows):
|
||||
result_row = []
|
||||
for j, tile in enumerate(row):
|
||||
# blend the above tile and the left tile
|
||||
# to the current tile and add the current tile to the result row
|
||||
if i > 0:
|
||||
tile = self.blend_v(rows[i - 1][j], tile, blend_extent)
|
||||
if j > 0:
|
||||
tile = self.blend_h(row[j - 1], tile, blend_extent)
|
||||
result_row.append(tile[:, :, :, :row_limit, :row_limit])
|
||||
result_rows.append(torch.cat(result_row, dim=4))
|
||||
|
||||
moments = torch.cat(result_rows, dim=3)
|
||||
posterior = DiagonalGaussianDistribution(moments)
|
||||
if return_moments:
|
||||
return moments
|
||||
return posterior
|
||||
|
||||
def tiled_decode2d(self, z):
|
||||
|
||||
overlap_size = int(self.tile_latent_min_size * (1 - self.tile_overlap_factor))
|
||||
blend_extent = int(self.tile_sample_min_size * self.tile_overlap_factor)
|
||||
row_limit = self.tile_sample_min_size - blend_extent
|
||||
|
||||
# Split z into overlapping 64x64 tiles and decode them separately.
|
||||
# The tiles have an overlap to avoid seams between tiles.
|
||||
rows = []
|
||||
for i in range(0, z.shape[3], overlap_size):
|
||||
row = []
|
||||
for j in range(0, z.shape[4], overlap_size):
|
||||
tile = z[
|
||||
:,
|
||||
:,
|
||||
:,
|
||||
i : i + self.tile_latent_min_size,
|
||||
j : j + self.tile_latent_min_size,
|
||||
]
|
||||
if self.use_quant_layer:
|
||||
tile = self.post_quant_conv(tile)
|
||||
decoded = self.decoder(tile)
|
||||
row.append(decoded)
|
||||
rows.append(row)
|
||||
result_rows = []
|
||||
for i, row in enumerate(rows):
|
||||
result_row = []
|
||||
for j, tile in enumerate(row):
|
||||
# blend the above tile and the left tile
|
||||
# to the current tile and add the current tile to the result row
|
||||
if i > 0:
|
||||
tile = self.blend_v(rows[i - 1][j], tile, blend_extent)
|
||||
if j > 0:
|
||||
tile = self.blend_h(row[j - 1], tile, blend_extent)
|
||||
result_row.append(tile[:, :, :, :row_limit, :row_limit])
|
||||
result_rows.append(torch.cat(result_row, dim=4))
|
||||
|
||||
dec = torch.cat(result_rows, dim=3)
|
||||
return dec
|
||||
|
||||
def enable_tiling(self, use_tiling: bool = True):
|
||||
self.use_tiling = use_tiling
|
||||
|
||||
def disable_tiling(self):
|
||||
self.enable_tiling(False)
|
||||
|
||||
def init_from_ckpt(self, path, ignore_keys=list()):
|
||||
sd = torch.load(path, map_location="cpu")
|
||||
print("init from " + path)
|
||||
|
||||
if "ema_state_dict" in sd and len(sd['ema_state_dict']) > 0 and os.environ.get("NOT_USE_EMA_MODEL", 0) == 0:
|
||||
print("Load from ema model!")
|
||||
sd = sd["ema_state_dict"]
|
||||
sd = {key.replace("module.", ""): value for key, value in sd.items()}
|
||||
elif "state_dict" in sd:
|
||||
print("Load from normal model!")
|
||||
if "gen_model" in sd["state_dict"]:
|
||||
sd = sd["state_dict"]["gen_model"]
|
||||
else:
|
||||
sd = sd["state_dict"]
|
||||
|
||||
keys = list(sd.keys())
|
||||
|
||||
for k in keys:
|
||||
for ik in ignore_keys:
|
||||
if k.startswith(ik):
|
||||
print("Deleting key {} from state_dict.".format(k))
|
||||
del sd[k]
|
||||
|
||||
miss, unexpected = self.load_state_dict(sd, strict=False)
|
||||
assert len(miss) == 0, f"miss key: {miss}"
|
||||
if len(unexpected) > 0:
|
||||
for i in unexpected:
|
||||
assert 'loss' in i, "unexpected key: {i}"
|
||||
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,44 @@
|
||||
import json
|
||||
import yaml
|
||||
from typing import TypeVar, Dict, Any
|
||||
from diffusers import ConfigMixin
|
||||
|
||||
T = TypeVar('T', bound='VideoBaseConfiguration')
|
||||
class VideoBaseConfiguration(ConfigMixin):
|
||||
config_name = "VideoBaseConfiguration"
|
||||
_nested_config_fields: Dict[str, Any] = {}
|
||||
|
||||
def __init__(self, **kwargs):
|
||||
pass
|
||||
|
||||
def to_dict(self) -> Dict[str, Any]:
|
||||
d = {}
|
||||
for key, value in vars(self).items():
|
||||
if isinstance(value, VideoBaseConfiguration):
|
||||
d[key] = value.to_dict() # Serialize nested VideoBaseConfiguration instances
|
||||
elif isinstance(value, tuple):
|
||||
d[key] = list(value)
|
||||
else:
|
||||
d[key] = value
|
||||
return d
|
||||
|
||||
def to_yaml_file(self, yaml_path: str):
|
||||
with open(yaml_path, 'w') as yaml_file:
|
||||
yaml.dump(self.to_dict(), yaml_file, default_flow_style=False)
|
||||
|
||||
@classmethod
|
||||
def load_from_yaml(cls: T, yaml_path: str) -> T:
|
||||
with open(yaml_path, 'r') as yaml_file:
|
||||
config_dict = yaml.safe_load(yaml_file)
|
||||
for field, field_type in cls._nested_config_fields.items():
|
||||
if field in config_dict:
|
||||
config_dict[field] = field_type.load_from_dict(config_dict[field])
|
||||
return cls(**config_dict)
|
||||
|
||||
@classmethod
|
||||
def load_from_dict(cls: T, config_dict: Dict[str, Any]) -> T:
|
||||
# Process nested configuration objects
|
||||
for field, field_type in cls._nested_config_fields.items():
|
||||
if field in config_dict:
|
||||
config_dict[field] = field_type.load_from_dict(config_dict[field])
|
||||
return cls(**config_dict)
|
||||
+107
@@ -0,0 +1,107 @@
|
||||
import os.path as osp
|
||||
import random
|
||||
from glob import glob
|
||||
|
||||
from torchvision import transforms
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.utils.data as data
|
||||
import torch.nn.functional as F
|
||||
from torchvision.transforms import Lambda
|
||||
|
||||
from ..dataset.transform import ToTensorVideo, CenterCropVideo
|
||||
from ..utils.dataset_utils import DecordInit
|
||||
|
||||
def TemporalRandomCrop(total_frames, size):
|
||||
"""
|
||||
Performs a random temporal crop on a video sequence.
|
||||
|
||||
This function randomly selects a continuous frame sequence of length `size` from a video sequence.
|
||||
`total_frames` indicates the total number of frames in the video sequence, and `size` represents the length of the frame sequence to be cropped.
|
||||
|
||||
Parameters:
|
||||
- total_frames (int): The total number of frames in the video sequence.
|
||||
- size (int): The length of the frame sequence to be cropped.
|
||||
|
||||
Returns:
|
||||
- (int, int): A tuple containing two integers. The first integer is the starting frame index of the cropped sequence,
|
||||
and the second integer is the ending frame index (inclusive) of the cropped sequence.
|
||||
"""
|
||||
rand_end = max(0, total_frames - size - 1)
|
||||
begin_index = random.randint(0, rand_end)
|
||||
end_index = min(begin_index + size, total_frames)
|
||||
return begin_index, end_index
|
||||
|
||||
def resize(x, resolution):
|
||||
height, width = x.shape[-2:]
|
||||
resolution = min(2 * resolution, height, width)
|
||||
aspect_ratio = width / height
|
||||
if width <= height:
|
||||
new_width = resolution
|
||||
new_height = int(resolution / aspect_ratio)
|
||||
else:
|
||||
new_height = resolution
|
||||
new_width = int(resolution * aspect_ratio)
|
||||
resized_x = F.interpolate(x, size=(new_height, new_width), mode='bilinear', align_corners=True, antialias=True)
|
||||
return resized_x
|
||||
|
||||
class VideoDataset(data.Dataset):
|
||||
""" Generic dataset for videos files stored in folders
|
||||
Returns BCTHW videos in the range [-0.5, 0.5] """
|
||||
video_exts = ['avi', 'mp4', 'webm']
|
||||
def __init__(self, video_folder, sequence_length, image_folder=None, train=True, resolution=64, sample_rate=1, dynamic_sample=True):
|
||||
|
||||
self.train = train
|
||||
self.sequence_length = sequence_length
|
||||
self.sample_rate = sample_rate
|
||||
self.resolution = resolution
|
||||
self.v_decoder = DecordInit()
|
||||
self.video_folder = video_folder
|
||||
self.dynamic_sample = dynamic_sample
|
||||
|
||||
self.transform = transforms.Compose([
|
||||
ToTensorVideo(),
|
||||
# Lambda(lambda x: resize(x, self.resolution)),
|
||||
CenterCropVideo(self.resolution),
|
||||
Lambda(lambda x: 2.0 * x - 1.0)
|
||||
])
|
||||
print('Building datasets...')
|
||||
self.samples = self._make_dataset()
|
||||
|
||||
def _make_dataset(self):
|
||||
samples = []
|
||||
samples += sum([glob(osp.join(self.video_folder, '**', f'*.{ext}'), recursive=True)
|
||||
for ext in self.video_exts], [])
|
||||
return samples
|
||||
|
||||
def __len__(self):
|
||||
return len(self.samples)
|
||||
|
||||
def __getitem__(self, idx):
|
||||
video_path = self.samples[idx]
|
||||
try:
|
||||
video = self.decord_read(video_path)
|
||||
video = self.transform(video) # T C H W -> T C H W
|
||||
video = video.transpose(0, 1) # T C H W -> C T H W
|
||||
return dict(video=video, label="")
|
||||
except Exception as e:
|
||||
print(f'Error with {e}, {video_path}')
|
||||
return self.__getitem__(random.randint(0, self.__len__()-1))
|
||||
|
||||
def decord_read(self, path):
|
||||
decord_vr = self.v_decoder(path)
|
||||
total_frames = len(decord_vr)
|
||||
# Sampling video frames
|
||||
if self.dynamic_sample:
|
||||
sample_rate = random.randint(1, self.sample_rate)
|
||||
else:
|
||||
sample_rate = self.sample_rate
|
||||
size = self.sequence_length * sample_rate
|
||||
start_frame_ind, end_frame_ind = TemporalRandomCrop(total_frames, size)
|
||||
# assert end_frame_ind - start_frame_ind >= self.num_frames
|
||||
frame_indice = np.linspace(start_frame_ind, end_frame_ind - 1, self.sequence_length, dtype=int)
|
||||
|
||||
video_data = decord_vr.get_batch(frame_indice).asnumpy()
|
||||
video_data = torch.from_numpy(video_data)
|
||||
video_data = video_data.permute(0, 3, 1, 2) # (T, H, W, C) -> (T C H W)
|
||||
return video_data
|
||||
+31
@@ -0,0 +1,31 @@
|
||||
class EMA:
|
||||
def __init__(self, model, decay):
|
||||
self.model = model
|
||||
self.decay = decay
|
||||
self.shadow = {}
|
||||
self.backup = {}
|
||||
|
||||
def register(self):
|
||||
for name, param in self.model.named_parameters():
|
||||
if param.requires_grad:
|
||||
self.shadow[name] = param.data.clone()
|
||||
|
||||
def update(self):
|
||||
for name, param in self.model.named_parameters():
|
||||
if name in self.shadow:
|
||||
new_average = (1.0 - self.decay) * param.data + self.decay * self.shadow[name]
|
||||
self.shadow[name] = new_average.clone()
|
||||
|
||||
def apply_shadow(self):
|
||||
for name, param in self.model.named_parameters():
|
||||
if name in self.shadow:
|
||||
self.backup[name] = param.data
|
||||
param.data = self.shadow[name]
|
||||
|
||||
def restore(self):
|
||||
for name, param in self.model.named_parameters():
|
||||
if name in self.shadow:
|
||||
param.data = self.backup[name]
|
||||
self.backup = {}
|
||||
|
||||
|
||||
@@ -0,0 +1 @@
|
||||
from .perceptual_loss import SimpleLPIPS, LPIPSWithDiscriminator, LPIPSWithDiscriminator3D
|
||||
@@ -0,0 +1,181 @@
|
||||
import functools
|
||||
import torch.nn as nn
|
||||
from ..modules.normalize import ActNorm
|
||||
from ..modules.conv import CausalConv3d
|
||||
from einops import rearrange
|
||||
|
||||
def weights_init(m):
|
||||
classname = m.__class__.__name__
|
||||
if classname.find('Conv') != -1:
|
||||
nn.init.normal_(m.weight.data, 0.0, 0.02)
|
||||
elif classname.find('BatchNorm') != -1:
|
||||
nn.init.normal_(m.weight.data, 1.0, 0.02)
|
||||
nn.init.constant_(m.bias.data, 0)
|
||||
|
||||
def weights_init_conv(m):
|
||||
if hasattr(m, 'conv'):
|
||||
m = m.conv
|
||||
classname = m.__class__.__name__
|
||||
if classname.find('Conv') != -1:
|
||||
nn.init.normal_(m.weight.data, 0.0, 0.02)
|
||||
elif classname.find('BatchNorm') != -1:
|
||||
nn.init.normal_(m.weight.data, 1.0, 0.02)
|
||||
nn.init.constant_(m.bias.data, 0)
|
||||
|
||||
class NLayerDiscriminator(nn.Module):
|
||||
"""Defines a PatchGAN discriminator as in Pix2Pix
|
||||
--> see https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/blob/master/models/networks.py
|
||||
"""
|
||||
def __init__(self, input_nc=3, ndf=64, n_layers=3, use_actnorm=False):
|
||||
"""Construct a PatchGAN discriminator
|
||||
Parameters:
|
||||
input_nc (int) -- the number of channels in input images
|
||||
ndf (int) -- the number of filters in the last conv layer
|
||||
n_layers (int) -- the number of conv layers in the discriminator
|
||||
norm_layer -- normalization layer
|
||||
"""
|
||||
super(NLayerDiscriminator, self).__init__()
|
||||
if not use_actnorm:
|
||||
norm_layer = nn.BatchNorm2d
|
||||
else:
|
||||
norm_layer = ActNorm
|
||||
if type(norm_layer) == functools.partial: # no need to use bias as BatchNorm2d has affine parameters
|
||||
use_bias = norm_layer.func != nn.BatchNorm2d
|
||||
else:
|
||||
use_bias = norm_layer != nn.BatchNorm2d
|
||||
|
||||
kw = 4
|
||||
padw = 1
|
||||
sequence = [nn.Conv2d(input_nc, ndf, kernel_size=kw, stride=2, padding=padw), nn.LeakyReLU(0.2, True)]
|
||||
nf_mult = 1
|
||||
nf_mult_prev = 1
|
||||
for n in range(1, n_layers): # gradually increase the number of filters
|
||||
nf_mult_prev = nf_mult
|
||||
nf_mult = min(2 ** n, 8)
|
||||
sequence += [
|
||||
nn.Conv2d(ndf * nf_mult_prev, ndf * nf_mult, kernel_size=kw, stride=2, padding=padw, bias=use_bias),
|
||||
norm_layer(ndf * nf_mult),
|
||||
nn.LeakyReLU(0.2, True)
|
||||
]
|
||||
|
||||
nf_mult_prev = nf_mult
|
||||
nf_mult = min(2 ** n_layers, 8)
|
||||
sequence += [
|
||||
nn.Conv2d(ndf * nf_mult_prev, ndf * nf_mult, kernel_size=kw, stride=1, padding=padw, bias=use_bias),
|
||||
norm_layer(ndf * nf_mult),
|
||||
nn.LeakyReLU(0.2, True)
|
||||
]
|
||||
|
||||
sequence += [
|
||||
nn.Conv2d(ndf * nf_mult, 1, kernel_size=kw, stride=1, padding=padw)] # output 1 channel prediction map
|
||||
self.main = nn.Sequential(*sequence)
|
||||
|
||||
def forward(self, input):
|
||||
"""Standard forward."""
|
||||
return self.main(input)
|
||||
|
||||
class NLayerDiscriminator3D(nn.Module):
|
||||
"""Defines a 3D PatchGAN discriminator as in Pix2Pix but for 3D inputs."""
|
||||
def __init__(self, input_nc=1, ndf=64, n_layers=3, use_actnorm=False):
|
||||
"""
|
||||
Construct a 3D PatchGAN discriminator
|
||||
|
||||
Parameters:
|
||||
input_nc (int) -- the number of channels in input volumes
|
||||
ndf (int) -- the number of filters in the last conv layer
|
||||
n_layers (int) -- the number of conv layers in the discriminator
|
||||
use_actnorm (bool) -- flag to use actnorm instead of batchnorm
|
||||
"""
|
||||
super(NLayerDiscriminator3D, self).__init__()
|
||||
if not use_actnorm:
|
||||
norm_layer = nn.BatchNorm3d
|
||||
else:
|
||||
raise NotImplementedError("Not implemented.")
|
||||
if type(norm_layer) == functools.partial:
|
||||
use_bias = norm_layer.func != nn.BatchNorm3d
|
||||
else:
|
||||
use_bias = norm_layer != nn.BatchNorm3d
|
||||
|
||||
kw = 3
|
||||
padw = 1
|
||||
sequence = [nn.Conv3d(input_nc, ndf, kernel_size=kw, stride=2, padding=padw), nn.LeakyReLU(0.2, True)]
|
||||
nf_mult = 1
|
||||
nf_mult_prev = 1
|
||||
for n in range(1, n_layers): # gradually increase the number of filters
|
||||
nf_mult_prev = nf_mult
|
||||
nf_mult = min(2 ** n, 8)
|
||||
sequence += [
|
||||
nn.Conv3d(ndf * nf_mult_prev, ndf * nf_mult, kernel_size=(kw, kw, kw), stride=(2 if n==1 else 1,2,2), padding=padw, bias=use_bias),
|
||||
norm_layer(ndf * nf_mult),
|
||||
nn.LeakyReLU(0.2, True)
|
||||
]
|
||||
|
||||
nf_mult_prev = nf_mult
|
||||
nf_mult = min(2 ** n_layers, 8)
|
||||
sequence += [
|
||||
nn.Conv3d(ndf * nf_mult_prev, ndf * nf_mult, kernel_size=(kw, kw, kw), stride=1, padding=padw, bias=use_bias),
|
||||
norm_layer(ndf * nf_mult),
|
||||
nn.LeakyReLU(0.2, True)
|
||||
]
|
||||
|
||||
sequence += [nn.Conv3d(ndf * nf_mult, 1, kernel_size=kw, stride=1, padding=padw)] # output 1 channel prediction map
|
||||
self.main = nn.Sequential(*sequence)
|
||||
|
||||
def forward(self, input):
|
||||
"""Standard forward."""
|
||||
return self.main(input)
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
# class NLayerDiscriminator3D(nn.Module):
|
||||
# """Defines a 3D PatchGAN discriminator as in Pix2Pix but for 3D inputs."""
|
||||
# def __init__(self, input_nc=1, ndf=64, n_layers=3, use_actnorm=False):
|
||||
# """
|
||||
# Construct a 3D PatchGAN discriminator
|
||||
|
||||
# Parameters:
|
||||
# input_nc (int) -- the number of channels in input volumes
|
||||
# ndf (int) -- the number of filters in the last conv layer
|
||||
# n_layers (int) -- the number of conv layers in the discriminator
|
||||
# use_actnorm (bool) -- flag to use actnorm instead of batchnorm
|
||||
# """
|
||||
# super(NLayerDiscriminator3D, self).__init__()
|
||||
# if not use_actnorm:
|
||||
# norm_layer = nn.BatchNorm3d
|
||||
# else:
|
||||
# raise NotImplementedError("Not implemented.")
|
||||
# if type(norm_layer) == functools.partial:
|
||||
# use_bias = norm_layer.func != nn.BatchNorm3d
|
||||
# else:
|
||||
# use_bias = norm_layer != nn.BatchNorm3d
|
||||
|
||||
# kw = 4
|
||||
# padw = 1
|
||||
# sequence = [CausalConv3d(input_nc, ndf, kernel_size=kw, stride=2, padding=padw), nn.LeakyReLU(0.2, True)]
|
||||
# nf_mult = 1
|
||||
# nf_mult_prev = 1
|
||||
# for n in range(1, n_layers): # gradually increase the number of filters
|
||||
# nf_mult_prev = nf_mult
|
||||
# nf_mult = min(2 ** n, 8)
|
||||
# sequence += [
|
||||
# CausalConv3d(ndf * nf_mult_prev, ndf * nf_mult, kernel_size=(kw, kw, kw), stride=(2 if n==1 else 1,2,2), padding=padw, bias=use_bias),
|
||||
# norm_layer(ndf * nf_mult),
|
||||
# nn.LeakyReLU(0.2, True)
|
||||
# ]
|
||||
|
||||
# nf_mult_prev = nf_mult
|
||||
# nf_mult = min(2 ** n_layers, 8)
|
||||
# sequence += [
|
||||
# CausalConv3d(ndf * nf_mult_prev, ndf * nf_mult, kernel_size=(kw, kw, kw), stride=1, padding=padw, bias=use_bias),
|
||||
# norm_layer(ndf * nf_mult),
|
||||
# nn.LeakyReLU(0.2, True)
|
||||
# ]
|
||||
|
||||
# sequence += [CausalConv3d(ndf * nf_mult, 1, kernel_size=kw, stride=1, padding=padw)] # output 1 channel prediction map
|
||||
# self.main = nn.Sequential(*sequence)
|
||||
|
||||
# def forward(self, input):
|
||||
# """Standard forward."""
|
||||
# return self.main(input)
|
||||
+120
@@ -0,0 +1,120 @@
|
||||
"""Stripped version of https://github.com/richzhang/PerceptualSimilarity/tree/master/models"""
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from torchvision import models
|
||||
from collections import namedtuple
|
||||
from ...utils.taming_download import get_ckpt_path
|
||||
|
||||
class LPIPS(nn.Module):
|
||||
# Learned perceptual metric
|
||||
def __init__(self, use_dropout=True):
|
||||
super().__init__()
|
||||
self.scaling_layer = ScalingLayer()
|
||||
self.chns = [64, 128, 256, 512, 512] # vg16 features
|
||||
self.net = vgg16(pretrained=True, requires_grad=False)
|
||||
self.lin0 = NetLinLayer(self.chns[0], use_dropout=use_dropout)
|
||||
self.lin1 = NetLinLayer(self.chns[1], use_dropout=use_dropout)
|
||||
self.lin2 = NetLinLayer(self.chns[2], use_dropout=use_dropout)
|
||||
self.lin3 = NetLinLayer(self.chns[3], use_dropout=use_dropout)
|
||||
self.lin4 = NetLinLayer(self.chns[4], use_dropout=use_dropout)
|
||||
self.load_from_pretrained()
|
||||
for param in self.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
def load_from_pretrained(self, name="vgg_lpips"):
|
||||
ckpt = get_ckpt_path(name, ".cache/lpips")
|
||||
self.load_state_dict(torch.load(ckpt, map_location=torch.device("cpu")), strict=False)
|
||||
print("loaded pretrained LPIPS loss from {}".format(ckpt))
|
||||
|
||||
@classmethod
|
||||
def from_pretrained(cls, name="vgg_lpips"):
|
||||
if name != "vgg_lpips":
|
||||
raise NotImplementedError
|
||||
model = cls()
|
||||
ckpt = get_ckpt_path(name)
|
||||
model.load_state_dict(torch.load(ckpt, map_location=torch.device("cpu")), strict=False)
|
||||
return model
|
||||
|
||||
def forward(self, input, target):
|
||||
in0_input, in1_input = (self.scaling_layer(input), self.scaling_layer(target))
|
||||
outs0, outs1 = self.net(in0_input), self.net(in1_input)
|
||||
feats0, feats1, diffs = {}, {}, {}
|
||||
lins = [self.lin0, self.lin1, self.lin2, self.lin3, self.lin4]
|
||||
for kk in range(len(self.chns)):
|
||||
feats0[kk], feats1[kk] = normalize_tensor(outs0[kk]), normalize_tensor(outs1[kk])
|
||||
diffs[kk] = (feats0[kk] - feats1[kk]) ** 2
|
||||
|
||||
res = [spatial_average(lins[kk].model(diffs[kk]), keepdim=True) for kk in range(len(self.chns))]
|
||||
val = res[0]
|
||||
for l in range(1, len(self.chns)):
|
||||
val += res[l]
|
||||
return val
|
||||
|
||||
|
||||
class ScalingLayer(nn.Module):
|
||||
def __init__(self):
|
||||
super(ScalingLayer, self).__init__()
|
||||
self.register_buffer('shift', torch.Tensor([-.030, -.088, -.188])[None, :, None, None])
|
||||
self.register_buffer('scale', torch.Tensor([.458, .448, .450])[None, :, None, None])
|
||||
|
||||
def forward(self, inp):
|
||||
return (inp - self.shift) / self.scale
|
||||
|
||||
|
||||
class NetLinLayer(nn.Module):
|
||||
""" A single linear layer which does a 1x1 conv """
|
||||
def __init__(self, chn_in, chn_out=1, use_dropout=False):
|
||||
super(NetLinLayer, self).__init__()
|
||||
layers = [nn.Dropout(), ] if (use_dropout) else []
|
||||
layers += [nn.Conv2d(chn_in, chn_out, 1, stride=1, padding=0, bias=False), ]
|
||||
self.model = nn.Sequential(*layers)
|
||||
|
||||
|
||||
class vgg16(torch.nn.Module):
|
||||
def __init__(self, requires_grad=False, pretrained=True):
|
||||
super(vgg16, self).__init__()
|
||||
vgg_pretrained_features = models.vgg16(pretrained=pretrained).features
|
||||
self.slice1 = torch.nn.Sequential()
|
||||
self.slice2 = torch.nn.Sequential()
|
||||
self.slice3 = torch.nn.Sequential()
|
||||
self.slice4 = torch.nn.Sequential()
|
||||
self.slice5 = torch.nn.Sequential()
|
||||
self.N_slices = 5
|
||||
for x in range(4):
|
||||
self.slice1.add_module(str(x), vgg_pretrained_features[x])
|
||||
for x in range(4, 9):
|
||||
self.slice2.add_module(str(x), vgg_pretrained_features[x])
|
||||
for x in range(9, 16):
|
||||
self.slice3.add_module(str(x), vgg_pretrained_features[x])
|
||||
for x in range(16, 23):
|
||||
self.slice4.add_module(str(x), vgg_pretrained_features[x])
|
||||
for x in range(23, 30):
|
||||
self.slice5.add_module(str(x), vgg_pretrained_features[x])
|
||||
if not requires_grad:
|
||||
for param in self.parameters():
|
||||
param.requires_grad = False
|
||||
|
||||
def forward(self, X):
|
||||
h = self.slice1(X)
|
||||
h_relu1_2 = h
|
||||
h = self.slice2(h)
|
||||
h_relu2_2 = h
|
||||
h = self.slice3(h)
|
||||
h_relu3_3 = h
|
||||
h = self.slice4(h)
|
||||
h_relu4_3 = h
|
||||
h = self.slice5(h)
|
||||
h_relu5_3 = h
|
||||
vgg_outputs = namedtuple("VggOutputs", ['relu1_2', 'relu2_2', 'relu3_3', 'relu4_3', 'relu5_3'])
|
||||
out = vgg_outputs(h_relu1_2, h_relu2_2, h_relu3_3, h_relu4_3, h_relu5_3)
|
||||
return out
|
||||
|
||||
|
||||
def normalize_tensor(x,eps=1e-10):
|
||||
norm_factor = torch.sqrt(torch.sum(x**2,dim=1,keepdim=True))
|
||||
return x/(norm_factor+eps)
|
||||
|
||||
|
||||
def spatial_average(x, keepdim=True):
|
||||
return x.mean([2,3],keepdim=keepdim)
|
||||
@@ -0,0 +1,389 @@
|
||||
import torch
|
||||
from torch import nn
|
||||
import torch.nn.functional as F
|
||||
from .lpips import LPIPS
|
||||
from einops import rearrange
|
||||
from .discriminator import NLayerDiscriminator, weights_init, NLayerDiscriminator3D
|
||||
|
||||
|
||||
def hinge_d_loss(logits_real, logits_fake):
|
||||
loss_real = torch.mean(F.relu(1.0 - logits_real))
|
||||
loss_fake = torch.mean(F.relu(1.0 + logits_fake))
|
||||
d_loss = 0.5 * (loss_real + loss_fake)
|
||||
return d_loss
|
||||
|
||||
|
||||
def vanilla_d_loss(logits_real, logits_fake):
|
||||
d_loss = 0.5 * (
|
||||
torch.mean(torch.nn.functional.softplus(-logits_real))
|
||||
+ torch.mean(torch.nn.functional.softplus(logits_fake))
|
||||
)
|
||||
return d_loss
|
||||
|
||||
|
||||
def hinge_d_loss_with_exemplar_weights(logits_real, logits_fake, weights):
|
||||
assert weights.shape[0] == logits_real.shape[0] == logits_fake.shape[0]
|
||||
loss_real = torch.mean(F.relu(1.0 - logits_real), dim=[1, 2, 3])
|
||||
loss_fake = torch.mean(F.relu(1.0 + logits_fake), dim=[1, 2, 3])
|
||||
loss_real = (weights * loss_real).sum() / weights.sum()
|
||||
loss_fake = (weights * loss_fake).sum() / weights.sum()
|
||||
d_loss = 0.5 * (loss_real + loss_fake)
|
||||
return d_loss
|
||||
|
||||
|
||||
def adopt_weight(weight, global_step, threshold=0, value=0.0):
|
||||
if global_step < threshold:
|
||||
weight = value
|
||||
return weight
|
||||
|
||||
|
||||
def measure_perplexity(predicted_indices, n_embed):
|
||||
# src: https://github.com/karpathy/deep-vector-quantization/blob/main/model.py
|
||||
# eval cluster perplexity. when perplexity == num_embeddings then all clusters are used exactly equally
|
||||
encodings = F.one_hot(predicted_indices, n_embed).float().reshape(-1, n_embed)
|
||||
avg_probs = encodings.mean(0)
|
||||
perplexity = (-(avg_probs * torch.log(avg_probs + 1e-10)).sum()).exp()
|
||||
cluster_use = torch.sum(avg_probs > 0)
|
||||
return perplexity, cluster_use
|
||||
|
||||
|
||||
def l1(x, y):
|
||||
return torch.abs(x - y)
|
||||
|
||||
|
||||
def l2(x, y):
|
||||
return torch.pow((x - y), 2)
|
||||
|
||||
|
||||
class LPIPSWithDiscriminator(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
disc_start,
|
||||
logvar_init=0.0,
|
||||
kl_weight=1.0,
|
||||
pixelloss_weight=1.0,
|
||||
perceptual_weight=1.0,
|
||||
# --- Discriminator Loss ---
|
||||
disc_num_layers=3,
|
||||
disc_in_channels=3,
|
||||
disc_factor=1.0,
|
||||
disc_weight=1.0,
|
||||
use_actnorm=False,
|
||||
disc_conditional=False,
|
||||
disc_loss="hinge",
|
||||
loss_type: str = "l1"
|
||||
):
|
||||
|
||||
super().__init__()
|
||||
assert disc_loss in ["hinge", "vanilla"]
|
||||
self.kl_weight = kl_weight
|
||||
self.pixel_weight = pixelloss_weight
|
||||
self.perceptual_loss = LPIPS().eval()
|
||||
self.perceptual_weight = perceptual_weight
|
||||
self.logvar = nn.Parameter(torch.ones(size=()) * logvar_init)
|
||||
|
||||
self.discriminator = NLayerDiscriminator(
|
||||
input_nc=disc_in_channels, n_layers=disc_num_layers, use_actnorm=use_actnorm
|
||||
).apply(weights_init)
|
||||
self.discriminator_iter_start = disc_start
|
||||
self.disc_loss = hinge_d_loss if disc_loss == "hinge" else vanilla_d_loss
|
||||
self.disc_factor = disc_factor
|
||||
self.discriminator_weight = disc_weight
|
||||
self.disc_conditional = disc_conditional
|
||||
self.loss_func = l1 if loss_type == "l1" else l2
|
||||
|
||||
def calculate_adaptive_weight(self, nll_loss, g_loss, last_layer=None):
|
||||
layer = last_layer if last_layer is not None else self.last_layer[0]
|
||||
|
||||
nll_grads = torch.autograd.grad(nll_loss, layer, retain_graph=True)[0]
|
||||
g_grads = torch.autograd.grad(g_loss, layer, retain_graph=True)[0]
|
||||
|
||||
d_weight = torch.norm(nll_grads) / (torch.norm(g_grads) + 1e-4)
|
||||
d_weight = torch.clamp(d_weight, 0.0, 1e4).detach()
|
||||
d_weight = d_weight * self.discriminator_weight
|
||||
return d_weight
|
||||
|
||||
def forward(
|
||||
self,
|
||||
inputs,
|
||||
reconstructions,
|
||||
posteriors,
|
||||
optimizer_idx,
|
||||
global_step,
|
||||
split="train",
|
||||
weights=None,
|
||||
last_layer=None,
|
||||
cond=None,
|
||||
):
|
||||
# GAN Part
|
||||
inputs = rearrange(inputs, "b c t h w -> (b t) c h w").contiguous()
|
||||
reconstructions = rearrange(
|
||||
reconstructions, "b c t h w -> (b t) c h w"
|
||||
).contiguous()
|
||||
if optimizer_idx == 0:
|
||||
rec_loss = self.loss_func(inputs, reconstructions)
|
||||
if self.perceptual_weight > 0:
|
||||
p_loss = self.perceptual_loss(inputs, reconstructions)
|
||||
rec_loss = rec_loss + self.perceptual_weight * p_loss
|
||||
nll_loss = rec_loss / torch.exp(self.logvar) + self.logvar
|
||||
weighted_nll_loss = nll_loss
|
||||
if weights is not None:
|
||||
weighted_nll_loss = weights * nll_loss
|
||||
weighted_nll_loss = torch.sum(weighted_nll_loss) / weighted_nll_loss.shape[0]
|
||||
nll_loss = torch.sum(nll_loss) / nll_loss.shape[0]
|
||||
kl_loss = posteriors.kl()
|
||||
kl_loss = torch.sum(kl_loss) / kl_loss.shape[0]
|
||||
|
||||
logits_fake = self.discriminator(reconstructions)
|
||||
g_loss = -torch.mean(logits_fake)
|
||||
if global_step >= self.discriminator_iter_start:
|
||||
if self.disc_factor > 0.0:
|
||||
d_weight = self.calculate_adaptive_weight(
|
||||
nll_loss, g_loss, last_layer=last_layer
|
||||
)
|
||||
else:
|
||||
d_weight = torch.tensor(1.0)
|
||||
else:
|
||||
d_weight = torch.tensor(0.0)
|
||||
g_loss = torch.tensor(0.0, requires_grad=True)
|
||||
|
||||
disc_factor = adopt_weight(
|
||||
self.disc_factor, global_step, threshold=self.discriminator_iter_start
|
||||
)
|
||||
loss = (
|
||||
weighted_nll_loss
|
||||
+ self.kl_weight * kl_loss
|
||||
+ d_weight * disc_factor * g_loss
|
||||
)
|
||||
log = {
|
||||
"{}/total_loss".format(split): loss.clone().detach().mean(),
|
||||
"{}/logvar".format(split): self.logvar.detach(),
|
||||
"{}/kl_loss".format(split): kl_loss.detach().mean(),
|
||||
"{}/nll_loss".format(split): nll_loss.detach().mean(),
|
||||
"{}/rec_loss".format(split): rec_loss.detach().mean(),
|
||||
"{}/d_weight".format(split): d_weight.detach(),
|
||||
"{}/disc_factor".format(split): torch.tensor(disc_factor),
|
||||
"{}/g_loss".format(split): g_loss.detach().mean(),
|
||||
}
|
||||
return loss, log
|
||||
|
||||
if optimizer_idx == 1:
|
||||
if cond is None:
|
||||
logits_real = self.discriminator(inputs.contiguous().detach())
|
||||
logits_fake = self.discriminator(reconstructions.contiguous().detach())
|
||||
else:
|
||||
logits_real = self.discriminator(
|
||||
torch.cat((inputs.contiguous().detach(), cond), dim=1)
|
||||
)
|
||||
logits_fake = self.discriminator(
|
||||
torch.cat((reconstructions.contiguous().detach(), cond), dim=1)
|
||||
)
|
||||
|
||||
disc_factor = adopt_weight(
|
||||
self.disc_factor, global_step, threshold=self.discriminator_iter_start
|
||||
)
|
||||
d_loss = disc_factor * self.disc_loss(logits_real, logits_fake)
|
||||
|
||||
log = {
|
||||
"{}/disc_loss".format(split): d_loss.clone().detach().mean(),
|
||||
"{}/logits_real".format(split): logits_real.detach().mean(),
|
||||
"{}/logits_fake".format(split): logits_fake.detach().mean(),
|
||||
}
|
||||
return d_loss, log
|
||||
|
||||
|
||||
class LPIPSWithDiscriminator3D(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
disc_start,
|
||||
logvar_init=0.0,
|
||||
kl_weight=1.0,
|
||||
pixelloss_weight=1.0,
|
||||
perceptual_weight=1.0,
|
||||
# --- Discriminator Loss ---
|
||||
disc_num_layers=3,
|
||||
disc_in_channels=3,
|
||||
disc_factor=1.0,
|
||||
disc_weight=1.0,
|
||||
use_actnorm=False,
|
||||
disc_conditional=False,
|
||||
disc_loss="hinge",
|
||||
learn_logvar: bool = False,
|
||||
loss_type: str = "l1"
|
||||
):
|
||||
|
||||
super().__init__()
|
||||
assert disc_loss in ["hinge", "vanilla"]
|
||||
self.kl_weight = kl_weight
|
||||
self.pixel_weight = pixelloss_weight
|
||||
self.perceptual_loss = LPIPS().eval()
|
||||
self.perceptual_weight = perceptual_weight
|
||||
self.logvar = nn.Parameter(
|
||||
torch.full((), logvar_init), requires_grad=learn_logvar
|
||||
)
|
||||
self.discriminator = NLayerDiscriminator3D(
|
||||
input_nc=disc_in_channels, n_layers=disc_num_layers, use_actnorm=use_actnorm
|
||||
).apply(weights_init)
|
||||
self.discriminator_iter_start = disc_start
|
||||
self.disc_loss = hinge_d_loss if disc_loss == "hinge" else vanilla_d_loss
|
||||
self.disc_factor = disc_factor
|
||||
self.discriminator_weight = disc_weight
|
||||
self.disc_conditional = disc_conditional
|
||||
self.loss_func = l1 if loss_type == "l1" else l2
|
||||
|
||||
def calculate_adaptive_weight(self, nll_loss, g_loss, last_layer=None):
|
||||
layer = last_layer if last_layer is not None else self.last_layer[0]
|
||||
|
||||
nll_grads = torch.autograd.grad(nll_loss, layer, retain_graph=True)[0]
|
||||
g_grads = torch.autograd.grad(g_loss, layer, retain_graph=True)[0]
|
||||
|
||||
d_weight = torch.norm(nll_grads) / (torch.norm(g_grads) + 1e-4)
|
||||
d_weight = torch.clamp(d_weight, 0.0, 1e4).detach()
|
||||
d_weight = d_weight * self.discriminator_weight
|
||||
return d_weight
|
||||
|
||||
def forward(
|
||||
self,
|
||||
inputs,
|
||||
reconstructions,
|
||||
posteriors,
|
||||
optimizer_idx,
|
||||
global_step,
|
||||
split="train",
|
||||
weights=None,
|
||||
last_layer=None,
|
||||
cond=None
|
||||
):
|
||||
|
||||
t = inputs.shape[2]
|
||||
# GAN Part
|
||||
if optimizer_idx == 0:
|
||||
inputs = rearrange(inputs, "b c t h w -> (b t) c h w").contiguous()
|
||||
reconstructions = rearrange(
|
||||
reconstructions, "b c t h w -> (b t) c h w"
|
||||
).contiguous()
|
||||
rec_loss = self.loss_func(inputs, reconstructions)
|
||||
if self.perceptual_weight > 0:
|
||||
p_loss = self.perceptual_loss(inputs, reconstructions)
|
||||
rec_loss = rec_loss + self.perceptual_weight * p_loss
|
||||
nll_loss = rec_loss / torch.exp(self.logvar) + self.logvar
|
||||
weighted_nll_loss = nll_loss
|
||||
if weights is not None:
|
||||
weighted_nll_loss = weights * nll_loss
|
||||
weighted_nll_loss = torch.sum(weighted_nll_loss) / weighted_nll_loss.shape[0]
|
||||
nll_loss = torch.sum(nll_loss) / nll_loss.shape[0]
|
||||
kl_loss = posteriors.kl()
|
||||
kl_loss = torch.sum(kl_loss) / kl_loss.shape[0]
|
||||
|
||||
inputs = rearrange(inputs, "(b t) c h w -> b c t h w", t=t).contiguous()
|
||||
reconstructions = rearrange(
|
||||
reconstructions, "(b t) c h w -> b c t h w", t=t
|
||||
).contiguous()
|
||||
|
||||
logits_fake = self.discriminator(reconstructions)
|
||||
g_loss = -torch.mean(logits_fake)
|
||||
if global_step >= self.discriminator_iter_start:
|
||||
if self.disc_factor > 0.0:
|
||||
d_weight = self.calculate_adaptive_weight(
|
||||
nll_loss, g_loss, last_layer=last_layer
|
||||
)
|
||||
else:
|
||||
d_weight = torch.tensor(1.0)
|
||||
else:
|
||||
d_weight = torch.tensor(0.0)
|
||||
g_loss = torch.tensor(0.0, requires_grad=True)
|
||||
|
||||
disc_factor = adopt_weight(
|
||||
self.disc_factor, global_step, threshold=self.discriminator_iter_start
|
||||
)
|
||||
loss = (
|
||||
weighted_nll_loss
|
||||
+ self.kl_weight * kl_loss
|
||||
+ d_weight * disc_factor * g_loss
|
||||
)
|
||||
log = {
|
||||
"{}/total_loss".format(split): loss.clone().detach().mean(),
|
||||
"{}/logvar".format(split): self.logvar.detach(),
|
||||
"{}/kl_loss".format(split): kl_loss.detach().mean(),
|
||||
"{}/nll_loss".format(split): nll_loss.detach().mean(),
|
||||
"{}/rec_loss".format(split): rec_loss.detach().mean(),
|
||||
"{}/d_weight".format(split): d_weight.detach(),
|
||||
"{}/disc_factor".format(split): torch.tensor(disc_factor),
|
||||
"{}/g_loss".format(split): g_loss.detach().mean(),
|
||||
}
|
||||
return loss, log
|
||||
elif optimizer_idx == 1:
|
||||
logits_real = self.discriminator(inputs.contiguous().detach())
|
||||
logits_fake = self.discriminator(reconstructions.contiguous().detach())
|
||||
|
||||
disc_factor = adopt_weight(
|
||||
self.disc_factor, global_step, threshold=self.discriminator_iter_start
|
||||
)
|
||||
|
||||
d_loss = disc_factor * self.disc_loss(logits_real, logits_fake)
|
||||
|
||||
log = {
|
||||
"{}/disc_loss".format(split): d_loss.clone().detach().mean(),
|
||||
"{}/logits_real".format(split): logits_real.detach().mean(),
|
||||
"{}/logits_fake".format(split): logits_fake.detach().mean(),
|
||||
}
|
||||
return d_loss, log
|
||||
|
||||
|
||||
class SimpleLPIPS(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
logvar_init=0.0,
|
||||
kl_weight=1.0,
|
||||
pixelloss_weight=1.0,
|
||||
perceptual_weight=1.0,
|
||||
disc_loss="hinge",
|
||||
learn_logvar: bool = False,
|
||||
**kwargs
|
||||
):
|
||||
|
||||
super().__init__()
|
||||
assert disc_loss in ["hinge", "vanilla"]
|
||||
self.kl_weight = kl_weight
|
||||
self.pixel_weight = pixelloss_weight
|
||||
self.perceptual_loss = LPIPS().eval()
|
||||
self.perceptual_weight = perceptual_weight
|
||||
self.logvar = nn.Parameter(
|
||||
torch.full((), logvar_init), requires_grad=learn_logvar
|
||||
)
|
||||
|
||||
def forward(
|
||||
self,
|
||||
inputs,
|
||||
reconstructions,
|
||||
posteriors,
|
||||
split="train",
|
||||
weights=None,
|
||||
):
|
||||
inputs = rearrange(inputs, "b c t h w -> (b t) c h w").contiguous()
|
||||
reconstructions = rearrange(
|
||||
reconstructions, "b c t h w -> (b t) c h w"
|
||||
).contiguous()
|
||||
rec_loss = torch.abs(inputs - reconstructions)
|
||||
if self.perceptual_weight > 0:
|
||||
p_loss = self.perceptual_loss(inputs, reconstructions)
|
||||
rec_loss = rec_loss + self.perceptual_weight * p_loss
|
||||
nll_loss = rec_loss / torch.exp(self.logvar) + self.logvar
|
||||
weighted_nll_loss = nll_loss
|
||||
if weights is not None:
|
||||
weighted_nll_loss = weights * nll_loss
|
||||
weighted_nll_loss = torch.sum(weighted_nll_loss) / weighted_nll_loss.shape[0]
|
||||
nll_loss = torch.sum(nll_loss) / nll_loss.shape[0]
|
||||
kl_loss = posteriors.kl()
|
||||
kl_loss = torch.sum(kl_loss) / kl_loss.shape[0]
|
||||
loss = weighted_nll_loss + self.kl_weight * kl_loss
|
||||
log = {
|
||||
"{}/total_loss".format(split): loss.clone().detach().mean(),
|
||||
"{}/logvar".format(split): self.logvar.detach(),
|
||||
"{}/kl_loss".format(split): kl_loss.detach().mean(),
|
||||
"{}/nll_loss".format(split): nll_loss.detach().mean(),
|
||||
"{}/rec_loss".format(split): rec_loss.detach().mean(),
|
||||
}
|
||||
if self.perceptual_weight > 0:
|
||||
log.update({"{}/p_loss".format(split): p_loss.detach().mean()})
|
||||
return loss, log
|
||||
@@ -0,0 +1,53 @@
|
||||
import torch
|
||||
from diffusers import ModelMixin, ConfigMixin
|
||||
from torch import nn
|
||||
import os
|
||||
import json
|
||||
import pytorch_lightning as pl
|
||||
from diffusers.configuration_utils import ConfigMixin
|
||||
from diffusers.models.modeling_utils import ModelMixin
|
||||
from typing import Optional, Union
|
||||
import glob
|
||||
|
||||
|
||||
class VideoBaseAE(ModelMixin, ConfigMixin):
|
||||
config_name = "config.json"
|
||||
|
||||
def __init__(self, *args, **kwargs) -> None:
|
||||
super().__init__(*args, **kwargs)
|
||||
|
||||
def encode(self, x: torch.Tensor, *args, **kwargs):
|
||||
pass
|
||||
|
||||
def decode(self, encoding: torch.Tensor, *args, **kwargs):
|
||||
pass
|
||||
|
||||
@property
|
||||
def num_training_steps(self) -> int:
|
||||
"""Total training steps inferred from datamodule and devices."""
|
||||
if self.trainer.max_steps:
|
||||
return self.trainer.max_steps
|
||||
|
||||
limit_batches = self.trainer.limit_train_batches
|
||||
batches = len(self.train_dataloader())
|
||||
batches = min(batches, limit_batches) if isinstance(limit_batches, int) else int(limit_batches * batches)
|
||||
|
||||
num_devices = max(1, self.trainer.num_gpus, self.trainer.num_processes)
|
||||
if self.trainer.tpu_cores:
|
||||
num_devices = max(num_devices, self.trainer.tpu_cores)
|
||||
|
||||
effective_accum = self.trainer.accumulate_grad_batches * num_devices
|
||||
return (batches // effective_accum) * self.trainer.max_epochs
|
||||
|
||||
@classmethod
|
||||
def from_pretrained(cls, pretrained_model_name_or_path: Optional[Union[str, os.PathLike]], **kwargs):
|
||||
ckpt_files = glob.glob(os.path.join(pretrained_model_name_or_path, '*.ckpt'))
|
||||
if ckpt_files:
|
||||
# Adapt to checkpoint
|
||||
last_ckpt_file = ckpt_files[-1]
|
||||
config_file = os.path.join(pretrained_model_name_or_path, cls.config_name)
|
||||
model = cls.from_config(config_file)
|
||||
model.init_from_ckpt(last_ckpt_file)
|
||||
return model
|
||||
else:
|
||||
return super().from_pretrained(pretrained_model_name_or_path, **kwargs)
|
||||
@@ -0,0 +1,6 @@
|
||||
from .block import Block
|
||||
from .attention import *
|
||||
from .conv import *
|
||||
from .normalize import *
|
||||
from .resnet_block import *
|
||||
from .updownsample import *
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user