
253 lines
14 KiB
Markdown
253 lines
14 KiB
Markdown
# Open-Sora Plan
|
||
|
||
[[Project Page]](https://pku-yuangroup.github.io/Open-Sora-Plan/) [[中文主页]](https://pku-yuangroup.github.io/Open-Sora-Plan/blog_cn.html)
|
||
|
||
[](https://discord.gg/fqpmStRX)
|
||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/issues/53#issuecomment-1980312563)
|
||
[](https://x.com/LinBin46984/status/1763476690385424554?s=20) <br>
|
||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/blob/main/LICENSE)
|
||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/graphs/contributors)
|
||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/commits/main/)
|
||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/pulls)
|
||
[](https://github.com/PKU-YuanGroup/Video-LLaVA/issues?q=is%3Aopen+is%3Aissue)
|
||
[](https://github.com/PKU-YuanGroup/Video-LLaVA/issues?q=is%3Aissue+is%3Aclosed) <br>
|
||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/stargazers) 
|
||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/network) 
|
||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/watchers) 
|
||
[](https://github.com/PKU-YuanGroup/Open-Sora-Plan/archive/refs/heads/main.zip)
|
||
|
||
|
||
|
||
|
||
## 💪 Goal
|
||
This project aims to create a simple and scalable repo, to reproduce [Sora](https://openai.com/sora) (OpenAI, but we prefer to call it "ClosedAI" ) and build knowledge about Video-VQVAE (VideoGPT) + DiT at scale. However, since we have limited resources, we deeply wish all open-source community can contribute to this project. Pull requests are welcome!!!
|
||
|
||
本项目希望通过开源社区的力量复现Sora,由北大-兔展AIGC联合实验室共同发起,当前我们资源有限仅搭建了基础架构,无法进行完整训练,希望通过开源社区逐步增加模块并筹集资源进行训练,当前版本离目标差距巨大,仍需持续完善和快速迭代,欢迎Pull request!!!
|
||
|
||
Project stages:
|
||
- Primary
|
||
1. Setup the codebase and train a un-conditional model on a landscape dataset.
|
||
2. Train models that boost resolution and duration.
|
||
|
||
- Extensions
|
||
3. Conduct text2video experiments on landscape dataset.
|
||
4. Train the 1080p model on video2text dataset.
|
||
5. Control model with more conditions.
|
||
|
||
|
||
<div style="display: flex; justify-content: center;">
|
||
<img src="assets/we_want_you.jpg" width=200>
|
||
<img src="assets/framework.jpg" width=600>
|
||
</div>
|
||
|
||
|
||
## 📰 News
|
||
**[2024.03.08]** We support the training code of text condition with 16 frames of 512x512. The code is mainly borrowed from [Latte](https://github.com/Vchitect/Latte).
|
||
|
||
**[2024.03.07]** We support training with 128 frames (when sample rate = 3, which is about 13 seconds) of 256x256, or 64 frames (which is about 6 seconds) of 512x512.
|
||
|
||
**[2024.03.05]** See our latest [todo](https://github.com/PKU-YuanGroup/Open-Sora-Plan?tab=readme-ov-file#todo), pull requests are welcome.
|
||
|
||
**[2024.03.04]** We re-organizes and modulizes our code to make it easy to [contribute](https://github.com/PKU-YuanGroup/Open-Sora-Plan?tab=readme-ov-file#how-to-contribute-to-the-open-sora-plan-community) to the project, to contribute please see the [Repo structure](https://github.com/PKU-YuanGroup/Open-Sora-Plan?tab=readme-ov-file#repo-structure).
|
||
|
||
**[2024.03.03]** We opened some [discussions](https://github.com/PKU-YuanGroup/Open-Sora-Plan/discussions) to clarify several issues.
|
||
|
||
**[2024.03.01]** Training code is available now! Learn more on our [project page](https://pku-yuangroup.github.io/Open-Sora-Plan/). Please feel free to watch 👀 this repository for the latest updates.
|
||
|
||
|
||
## ✊ Todo
|
||
|
||
#### Setup the codebase and train a unconditional model on landscape dataset
|
||
- [x] Fix typos & Update readme. 🤝 Thanks to [@mio2333](https://github.com/mio2333), [@CreamyLong](https://github.com/CreamyLong), [@chg0901](https://github.com/chg0901), [@Nyx-177](https://github.com/Nyx-177), [@HowardLi1984](https://github.com/HowardLi1984), [@sennnnn](https://github.com/sennnnn)
|
||
- [x] Setup repo-structure.
|
||
- [ ] Add docker file. ⌛ [WIP]
|
||
- [ ] Enable type hints for functions. 🙏 **[Need your contribution]**
|
||
- [x] Add Video-VQGAN model, which is borrowed from [VideoGPT](https://github.com/wilson1yan/VideoGPT).
|
||
- [x] Support variable aspect ratios, resolutions, durations training on [DiT](https://github.com/facebookresearch/DiT).
|
||
- [x] Support Dynamic mask input inspired by [FiT](https://github.com/whlzy/FiT).
|
||
- [x] Add class-conditioning on embeddings.
|
||
- [x] Incorporating [Latte](https://github.com/Vchitect/Latte) as main codebase.
|
||
- [x] Add VAE model, which is borrowed from [Stable Diffusion](https://github.com/CompVis/latent-diffusion).
|
||
- [x] Joint dynamic mask input with VAE.
|
||
- [ ] Add VQVAE from [VQGAN](https://github.com/CompVis/taming-transformers). 🙏 **[Need your contribution]**
|
||
- [ ] Make the codebase ready for the cluster training. Add SLURM scripts. 🙏 **[Need your contribution]**
|
||
- [x] Refactor VideoGPT. 🤝 Thanks to [@qqingzheng](https://github.com/qqingzheng), [@luo3300612](https://github.com/luo3300612)
|
||
- [x] Add sampling script.
|
||
- [x] Incorporate [SiT](https://github.com/willisma/SiT). 🤝 Thanks to [@khan-yin](https://github.com/khan-yin)
|
||
- [ ] Add eavluation scripts (FVD, CLIP score). 🙏 **[Need your contribution]**
|
||
|
||
#### Train models that boost resolution and duration
|
||
- [ ] Add [PI](https://arxiv.org/abs/2306.15595) to support out-of-domain size. 🙏 **[Need your contribution]**
|
||
- [ ] Add 2D RoPE to improve generalization ability as [FiT](https://github.com/whlzy/FiT). 🙏 **[Need your contribution]**
|
||
- [ ] Train a **low dimension** Video-AE, whether it is VAE or VQVAE. 🚀 **[Require more computation]**
|
||
- [x] Extract offline feature.
|
||
- [x] Train with offline feature.
|
||
- [x] Add frame interpolation model. 🤝 Thanks to [@yunyangge](https://github.com/yunyangge)
|
||
- [x] Add super resolution model. 🤝 Thanks to [@Linzy19](https://github.com/Linzy19)
|
||
- [x] Add accelerate to automatically manage training.
|
||
- [ ] Joint training with images. 🙏 **[Need your contribution]**
|
||
- [ ] Incorporate [NaViT](https://arxiv.org/abs/2307.06304). 🙏 **[Need your contribution]**
|
||
- [ ] Add [FreeNoise](https://github.com/arthur-qiu/FreeNoise-LaVie) support for training-free longer video generation. 🙏 **[Need your contribution]**
|
||
|
||
#### Conduct text2video experiments on landscape dataset.
|
||
- [x] Finish data loading, pre-processing utils.
|
||
- [x] Add T5 support.
|
||
- [ ] Add CLIP support. 🙏 **[Need your contribution]**
|
||
- [x] Add text2image training script.
|
||
- [ ] Add prompt captioner. 🙏 **[Need your contribution]** 🚀 **[Require more computation]**
|
||
|
||
#### Train the 1080p model on video2text dataset
|
||
- [ ] Looking for a suitable dataset, welcome to discuss and recommend. 🙏 **[Need your contribution]**
|
||
- [ ] Add synthetic video created by game engines or 3D representations. 🙏 **[Need your contribution]**
|
||
- [ ] Finish data loading, and pre-processing utils. ⌛ [WIP]
|
||
- [ ] Support memory friendly training.
|
||
- [x] Add flash-attention2 from pytorch.
|
||
- [x] Add xformers.
|
||
- [x] Support mixed precision training.
|
||
- [x] Add gradient checkpoint.
|
||
- [x] Support for ReBased and Ring attention. 🤝 Thanks to [@kabachuha](https://github.com/kabachuha)
|
||
- [ ] Train using the deepspeed engine. 🙏 **[Need your contribution]**
|
||
- [ ] Integrate with [Colossal-AI](https://github.com/PKU-YuanGroup/Open-Sora-Plan/issues/59#issue-2170735221) for a cheaper, faster, and more efficient. 🙏 **[Need your contribution]**
|
||
- [ ] Train with a text condition. Here we could conduct different experiments:
|
||
- [ ] Train with T5 conditioning. 🚀 **[Require more computation]**
|
||
- [ ] Train with CLIP conditioning. 🚀 **[Require more computation]**
|
||
- [ ] Train with CLIP + T5 conditioning (probably costly during training and experiments). 🚀 **[Require more computation]**
|
||
|
||
#### Control model with more condition
|
||
- [ ] Load pretrained weights from [PixArt-α](https://github.com/PixArt-alpha/PixArt-alpha). ⌛ [WIP]
|
||
- [ ] Incorporating [ControlNet](https://github.com/lllyasviel/ControlNet). 🙏 **[Need your contribution]**
|
||
|
||
## 📂 Repo structure (WIP)
|
||
```
|
||
├── README.md
|
||
├── docs
|
||
│ ├── Data.md -> Datasets description.
|
||
│ ├── Contribution_Guidelines.md -> Contribution guidelines description.
|
||
├── scripts -> All scripts.
|
||
├── opensora
|
||
│ ├── dataset
|
||
│ ├── models
|
||
│ │ ├── ae -> Compress videos to latents
|
||
│ │ │ ├── imagebase
|
||
│ │ │ │ ├── vae
|
||
│ │ │ │ └── vqvae
|
||
│ │ │ └── videobase
|
||
│ │ │ ├── vae
|
||
│ │ │ └── vqvae
|
||
│ │ ├── captioner
|
||
│ │ ├── diffusion -> Denoise latents
|
||
│ │ │ ├── diffusion
|
||
│ │ │ ├── dit
|
||
│ │ │ ├── latte
|
||
│ │ │ └── unet
|
||
│ │ ├── frame_interpolation
|
||
│ │ └── super_resolution
|
||
│ ├── sample
|
||
│ ├── train -> Training code
|
||
│ └── utils
|
||
```
|
||
|
||
## 🛠️ Requirements and Installation
|
||
|
||
The requirements are as follows.
|
||
|
||
* Python >= 3.8
|
||
* CUDA Version >= 11.7
|
||
* Install required packages:
|
||
|
||
```
|
||
git clone https://github.com/PKU-YuanGroup/Open-Sora-Plan
|
||
cd Open-Sora-Plan
|
||
conda create -n opensora python=3.8 -y
|
||
conda activate opensora
|
||
pip install -e .
|
||
```
|
||
|
||
## 🗝️ Usage
|
||
|
||
### Datasets
|
||
Refer to [Data.md](docs/Data.md)
|
||
|
||
|
||
### Video-VQVAE (VideoGPT)
|
||
|
||
#### Training
|
||
|
||
To train VQVAE, run the script:
|
||
|
||
```
|
||
scripts/train_vqvae.sh
|
||
```
|
||
|
||
You can modify the training parameters within the script. For training parameters, please refer to [transformers.TrainingArguments](https://huggingface.co/docs/transformers/v4.38.2/en/main_classes/trainer#transformers.TrainingArguments). Other parameters are explained as follows:
|
||
|
||
##### VQ-VAE Specific Settings
|
||
|
||
* `--embedding_dim`: number of dimensions for codebooks embeddings
|
||
* `--n_codes 2048`: number of codes in the codebook
|
||
* `--n_hiddens 240`: number of hidden features in the residual blocks
|
||
* `--n_res_layers 4`: number of residual blocks
|
||
* `--downsample "4,4,4"`: T H W downsampling stride of the encoder
|
||
|
||
##### Dataset Settings
|
||
* `--data_path <path>`: path to an `hdf5` file or a folder containing `train` and `test` folders with subdirectories of videos
|
||
* `--resolution 128`: spatial resolution to train on
|
||
* `--sequence_length 16`: temporal resolution, or video clip length
|
||
|
||
#### Reconstructing
|
||
|
||
```Python
|
||
python examples/rec_video.py --video-path "assets/origin_video_0.mp4" --rec-path "rec_video_0.mp4" --num-frames 500 --sample-rate 1
|
||
```
|
||
```Python
|
||
python examples/rec_video.py --video-path "assets/origin_video_1.mp4" --rec-path "rec_video_1.mp4" --resolution 196 --num-frames 600 --sample-rate 1
|
||
```
|
||
|
||
We present four reconstructed videos in this demonstration, arranged from left to right as follows:
|
||
|
||
| **3s 596x336** | **10s 256x256** | **18s 196x196** | **24s 168x96** |
|
||
| --- | --- | --- | --- |
|
||
| <img src="assets/rec_video_2.gif"> | <img src="assets/rec_video_0.gif"> | <img src="assets/rec_video_1.gif"> | <img src="assets/rec_video_3.gif"> |
|
||
|
||
#### Others
|
||
|
||
Please refer to the document [VQVAE](docs/VQVAE.md).
|
||
|
||
### VideoDiT (DiT)
|
||
|
||
#### Training
|
||
```
|
||
sh scripts/train.sh
|
||
```
|
||
|
||
<p align="center">
|
||
<img src="assets/loss.jpg" width=60%>
|
||
</p>
|
||
|
||
#### Sampling
|
||
```
|
||
sh scripts/sample.sh
|
||
```
|
||
|
||
## 🤝 How to Contribute to the Open-Sora Plan Community
|
||
We greatly appreciate your contributions to the Open-Sora Plan open-source community and helping us make it even better than it is now!
|
||
|
||
For more details, please refer to the [Contribution Guidelines](docs/Contribution_Guidelines.md)
|
||
|
||
|
||
## 👍 Acknowledgement
|
||
* [Latte](https://github.com/Vchitect/Latte): The **main codebase** we built upon and it is an wonderful video gererated model.
|
||
* [DiT](https://github.com/facebookresearch/DiT): Scalable Diffusion Models with Transformers.
|
||
* [VideoGPT](https://github.com/wilson1yan/VideoGPT): Video Generation using VQ-VAE and Transformers.
|
||
* [FiT](https://github.com/whlzy/FiT): Flexible Vision Transformer for Diffusion Model.
|
||
* [Positional Interpolation](https://arxiv.org/abs/2306.15595): Extending Context Window of Large Language Models via Positional Interpolation.
|
||
|
||
|
||
## 🔒 License
|
||
* The service is a research preview intended for non-commercial use only. See [LICENSE](LICENSE) for details.
|
||
|
||
|
||
## ✨ Star History
|
||
|
||
[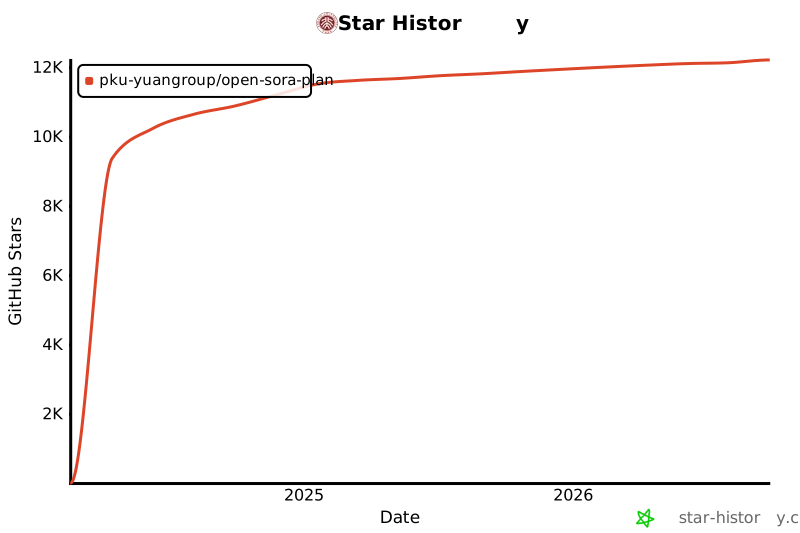](https://star-history.com/#PKU-YuanGroup/Open-Sora-Plan&Date)
|