docs: update README.md
This commit is contained in:
 Jeffrey Wu

Binary file not shown.
|
After Width: | Height: | Size: 125 KiB |

Binary file not shown.
|
After Width: | Height: | Size: 142 KiB |

Binary file not shown.
|
After Width: | Height: | Size: 119 KiB |
@@ -2,6 +2,8 @@
|
||||
|
||||
> Next generation face toolkit for ComfyUI.
|
||||
|
||||
This project is under development. There may be compatibility issues in future upgrades. If you encounter any problems, please create an issue, thanks.
|
||||
|
||||
## Installation
|
||||
|
||||
### Install custom node
|
||||
@@ -13,12 +15,43 @@ pip install -r requirements.txt
|
||||
|
||||
### Download model
|
||||
|
||||
All models is same as [facefusion](https://github.com/facefusion/facefusion).
|
||||
All models is same as [facefusion](https://github.com/facefusion/facefusion) which can be found in [facefusion assets](https://github.com/facefusion/facefusion-assets).
|
||||
|
||||
Download what your needs models from [facefusion assets](https://github.com/facefusion/facefusion-assets)
|
||||
Now it will use the following model by default. In the future, dynamic model selection will be supported. Please download the model based on the following directory structure.
|
||||
|
||||
Put all into directory `CmofyUI/models/faceless`.
|
||||
|
||||
```
|
||||
|-- face_detector
|
||||
| `-- yoloface_8n.onnx
|
||||
|-- face_landmarker
|
||||
| |-- 2dfan4.onnx
|
||||
| `-- face_landmarker_68_5.onnx
|
||||
|-- face_recognizer
|
||||
| `-- arcface_w600k_r50.onnx
|
||||
|-- face_swapper
|
||||
| |-- inswapper_128.onnx
|
||||
| `-- inswapper_128_fp16.onnx
|
||||
|-- gender_age.onnx
|
||||
`-- rmbg.pth
|
||||
```
|
||||
|
||||
## Example workflows
|
||||
|
||||
### Image face swap
|
||||
|
||||
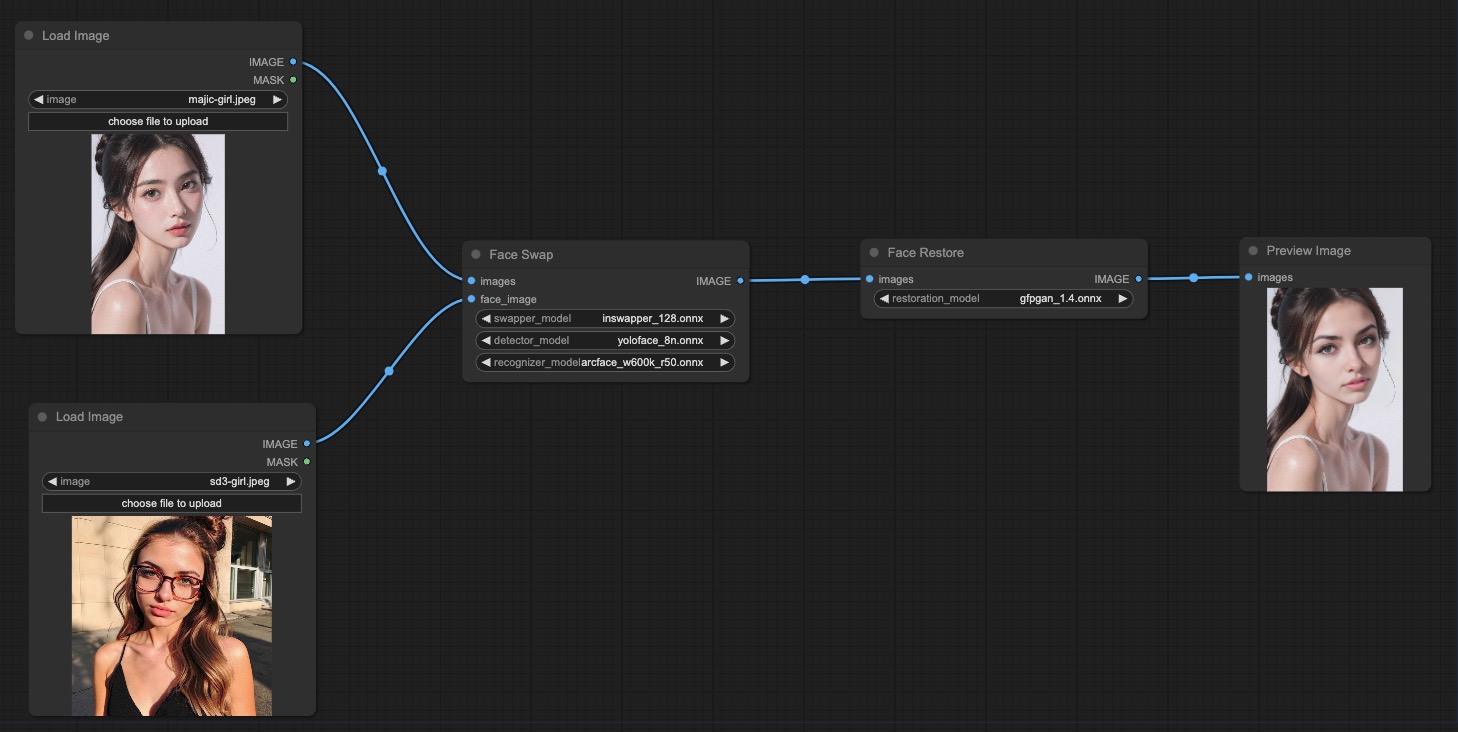
|
||||
|
||||
### Video face swap
|
||||
|
||||
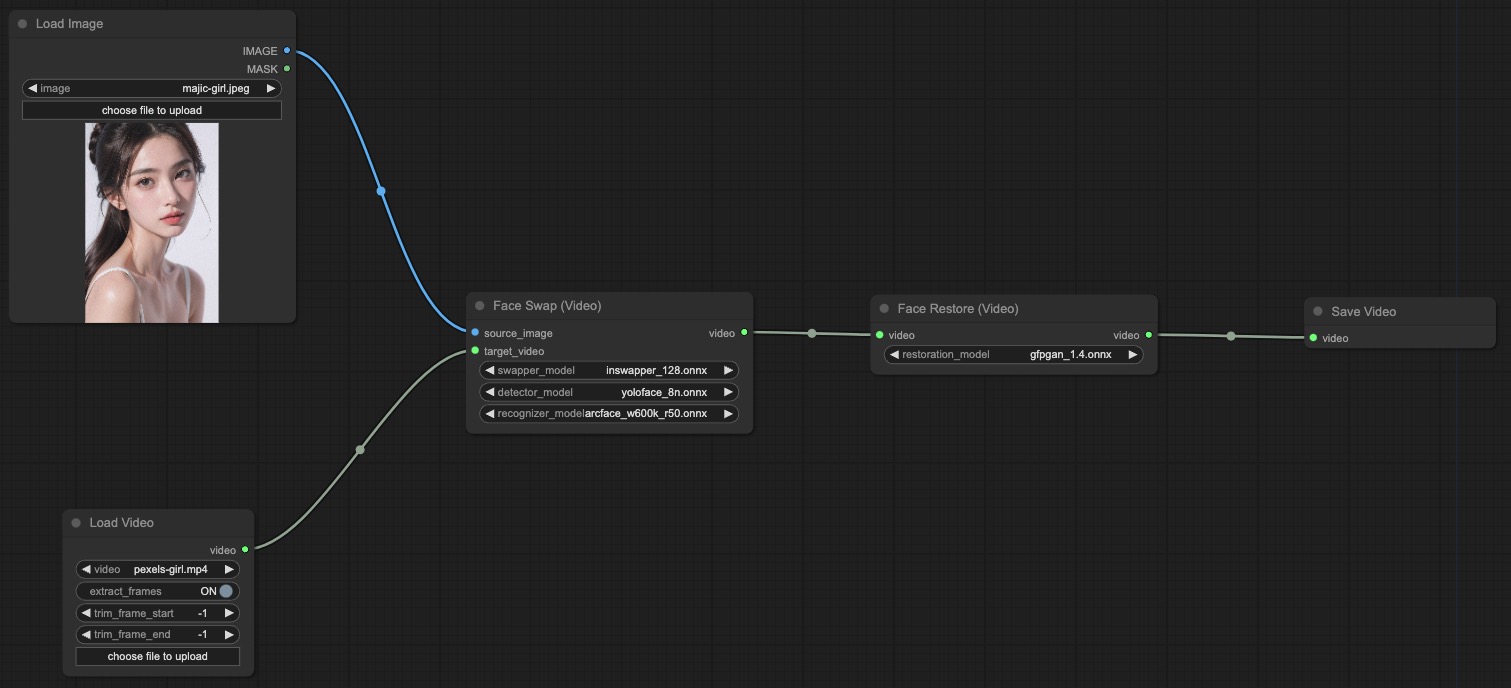
|
||||
|
||||
### Load frames to preview image
|
||||
|
||||

|
||||
|
||||
It doesn't support preview video for now. All video will be save in directory `output/faceless`.
|
||||
|
||||
## Thanks and Credits
|
||||
|
||||
Thanks to [Facefusion](https://github.com/facefusion/facefusion). This project is based on facefusion to implenment a special version for ComfyUI.
|
||||
|
||||
+1
-1
@@ -106,7 +106,7 @@ def restore_audio(video_path: str, audio_path: str, output_path: str, output_vid
|
||||
if trim_frame_end is not None:
|
||||
end_time = trim_frame_end / output_video_fps
|
||||
commands.extend([ '-to', str(end_time) ])
|
||||
commands.extend([ '-i', audio_path, '-c', 'copy', '-map', '0:v:0', '-map', '1:a:0', '-shortest', '-y', output_path ])
|
||||
commands.extend([ '-i', audio_path, '-c', 'copy', '-map', '0:v:0', '-map', '1:a?:0', '-shortest', '-y', output_path ])
|
||||
return run_ffmpeg(commands)
|
||||
|
||||
def map_amf_preset(output_video_preset : OutputVideoPreset) -> str:
|
||||
|
||||
@@ -47,8 +47,12 @@ class NodesRemoveBackground:
|
||||
processed_images.append(new_im_tensor)
|
||||
processed_masks.append(pil_im_tensor)
|
||||
|
||||
new_ims = torch.cat(processed_images, dim=0)
|
||||
new_masks = torch.cat(processed_masks, dim=0)
|
||||
if len(processed_images) > 1:
|
||||
new_ims = torch.cat(processed_images, dim=0)
|
||||
new_masks = torch.cat(processed_masks, dim=0)
|
||||
else:
|
||||
new_ims = processed_images[0]
|
||||
new_masks = processed_masks[0]
|
||||
return (new_ims, new_masks)
|
||||
|
||||
def remove_background(self, orig_image):
|
||||
|
||||
Reference in New Issue
Block a user