
ComfyUI-B-LoRA (Working in Progress)
A ComfyUI custom node that loads and applies B-LoRA models.
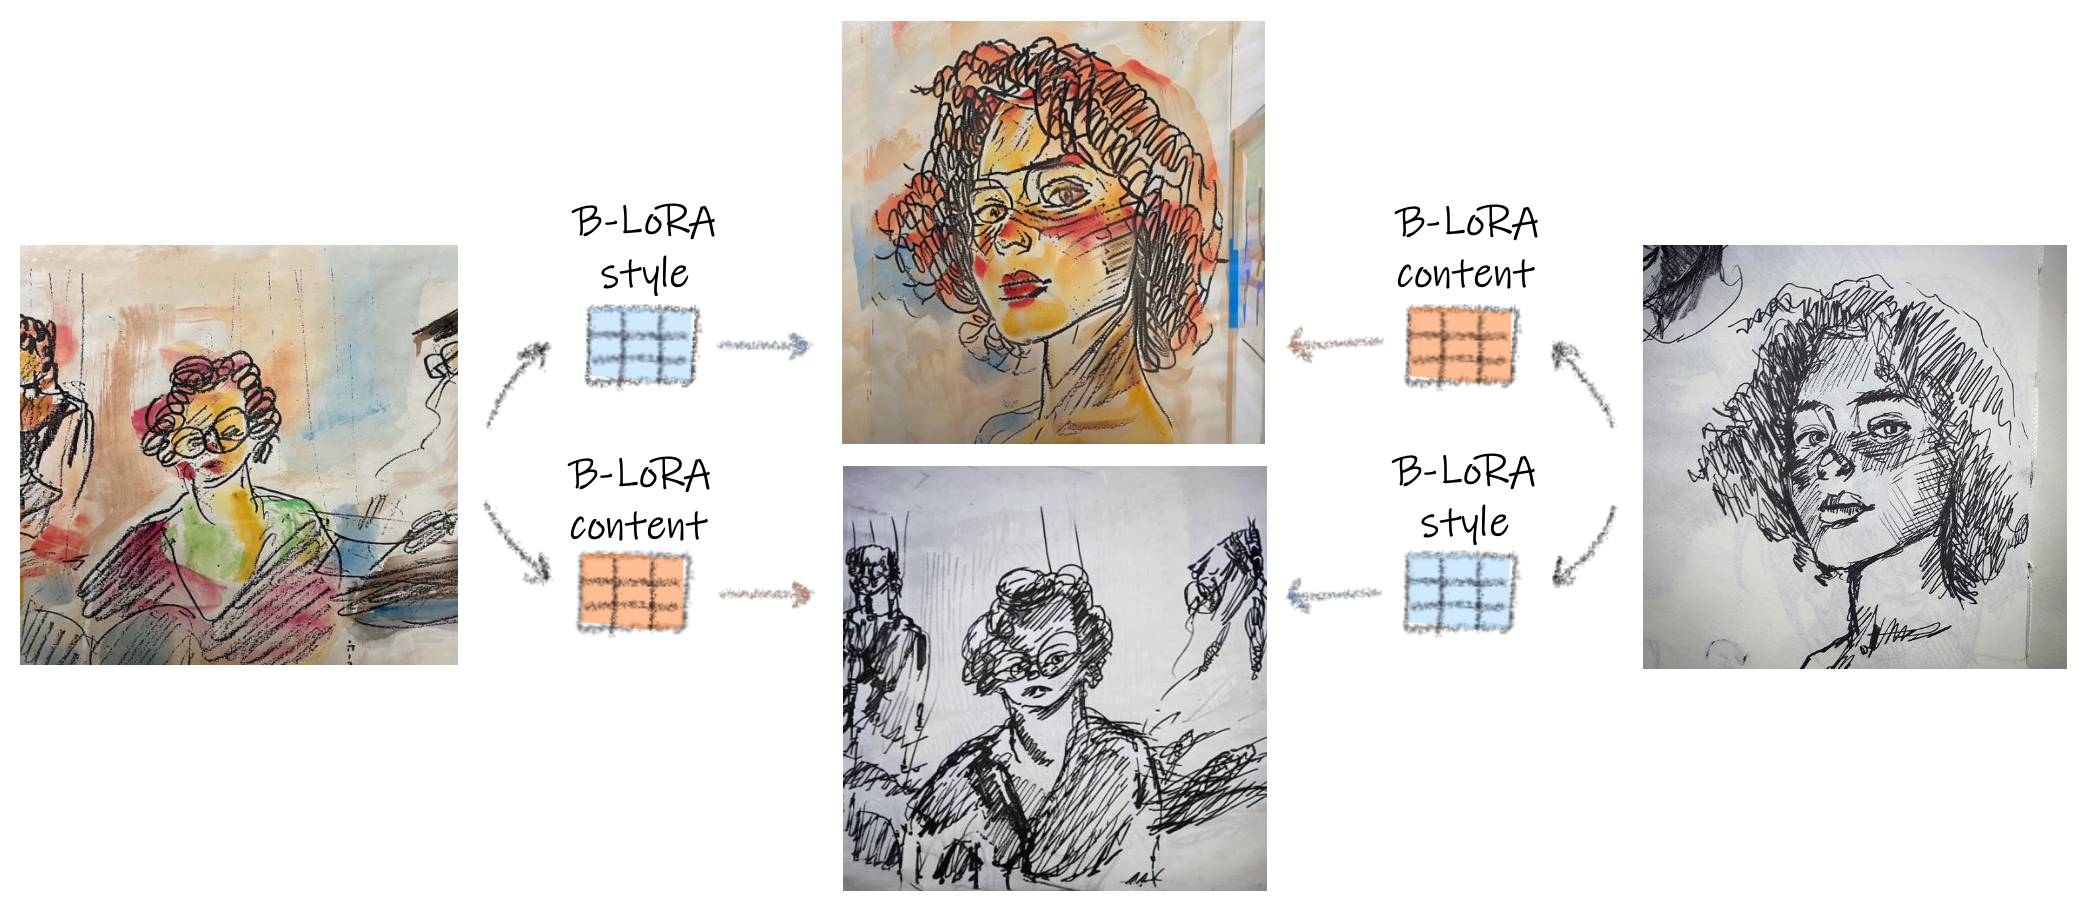
What is B-LoRA?
B-LoRA: By implicitly decomposing a single image into its style and content representation captured by B-LoRA, we can perform high quality style-content mixing and even swapping the style and content between two stylized images.
-
🌐 Website: https://b-lora.github.io/B-LoRA/
-
Currently B-LoRA models only works with SDXL (
sdxl_base_1.0).
Advantages of B-LoRA
-
Can apply
StyleorContent, or both. -
Much smaller model files. (~100M for SDXL B-LoRAs)
-
One B-LoRA only needs one image as training dataset and 15 minutes to train. (on a single RTX 4090)
Please share your B-LoRA models on Civit.ai or HuggingFace!
Workflow Examples
A Single Load B-LoRA node
 🌟
<s> is the training prompt for one B-Lora colorful-squirrel
A B-LoRA for Style, and another for Content
 🌟
<s> is the training prompt for one B-Lora colorful-squirrel, and <p> is the training prompt for the other pencil-boy.
B-LoRA models used in the workflows can be downloaded here:
https://huggingface.co/sida/B-LoRA-examples/tree/main
Credit goes to:
Citation
If you use B-LoRA in your research, please cite the authors' paper:
@misc{frenkel2024implicit,
      title={Implicit Style-Content Separation using B-LoRA},
      author={Yarden Frenkel and Yael Vinker and Ariel Shamir and Daniel Cohen-Or},
      year={2024},
      eprint={2403.14572},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}