Added support for gpu processing, set it as default. Much faster than cpu
This commit is contained in:
 Luis Quesada
@@ -1,6 +1,6 @@
|
||||
ComfyUI-Inpaint-CropAndStitch
|
||||
|
||||
Copyright (c) 2024-2025, Luis Quesada Torres - https://github.com/lquesada | www.luisquesada.com
|
||||
Copyright (c) 2024-2026, Luis Quesada Torres - https://github.com/lquesada | www.luisquesada.com
|
||||
|
||||
Check ComfyUI here: https://github.com/comfyanonymous/ComfyUI
|
||||
|
||||
@@ -23,6 +23,14 @@ The main advantages of inpainting only in a masked area with these nodes are:
|
||||
- It does not modify the unmasked part of the image, not even passing it through VAE encode and decode.
|
||||
- It takes care of blending automatically.
|
||||
|
||||
# Support me!
|
||||
|
||||
GenAI is not just for the sake of GenAI, but to unblock creativity and empower humans. I am not only a developer; I use GenAI myself to do **more** things **better** than I could otherwise do.
|
||||
|
||||
Do you like this node? Check, listen to, or follow my GenAI music project [**Windlereye** on Spotify](https://open.spotify.com/artist/6GdiI8ZKeWhSY73WWOhbep) to support me!
|
||||
|
||||
[](https://open.spotify.com/artist/6GdiI8ZKeWhSY73WWOhbep)
|
||||
|
||||
# Video Tutorial
|
||||
|
||||
[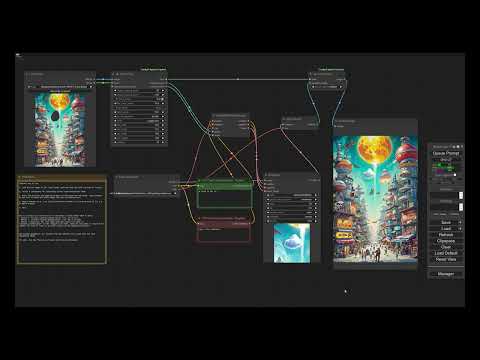](https://www.youtube.com/watch?v=mI0UWm7BNtQ)
|
||||
@@ -43,6 +51,7 @@ Note: this video tutorial is for the previous version of the nodes, but still it
|
||||
- `context_from_mask_extend_factor`: Extends the context area by a factor of the size of the mask. The higher this value is, the more area will be cropped around the mask for the model to have more context. 1 means do not grow. 2 means grow the same size of the mask across every direction.
|
||||
- `output_resize_to_target_size`: Forces that the cropped image has a specific resolution. This may involve resizing and extending out of the original image, but the stitch node reverts those changes to integrate the image seamlessly.
|
||||
- `output_padding`: Ensures that the cropped image width and height are a multiple of this padding value. Models require images to be padded to a certain value (8, 16, 32) to function properly.
|
||||
- `device_mode`: `cpu (compatible)` should always work but is slow, `gpu (much faster)` is much faster but may not work in all setups. Default is GPU given the performance improvements.
|
||||
|
||||
## Example (Stable Diffusion)
|
||||
This example inpaints by sampling on a small section of the larger image, upscaling to fit 512x512, then stitching and blending back in the original image.
|
||||
@@ -91,6 +100,9 @@ Enable "resize to target size" and set it to a preferred resolution for your mod
|
||||
If you mask an area and you can still see the original image through the rendered image, it is **very likely** that your mask is not fully opaque. Even if it looks fully opaque - the human brain cannot tell a difference between many shades of grey. Please make sure that the mask is 100% opaque, e.g. take a screenshot, check pixel values for 255, 255, 255 or #FFFFFF. If you use mask fill holes, check that the entire boundary is 255, 255, 255 or #FFFFFF e.g. with the fuzzy select tool in Gimp with threshold 0.
|
||||
|
||||
# Changelog
|
||||
## 2026-01-09
|
||||
- Huge performance improvement of 30x-100x by adding GPU support (new default is GPU, CPU is available as an option for fallback).
|
||||
- Clean up: Removed the long-deprecated old versions.
|
||||
## 2025-04-06
|
||||
- Published the improved version of the Crop and Stitch nodes.
|
||||
- Improved: Stitching is now way more precise. In the previous version, stitching an image back into place could shift it by one pixel. That will not happen anymore.
|
||||
|
||||
+2
-20
@@ -1,34 +1,16 @@
|
||||
from .inpaint_cropandstitch import InpaintCropImproved
|
||||
from .inpaint_cropandstitch import InpaintStitchImproved
|
||||
|
||||
# OLD
|
||||
from .inpaint_cropandstitch_old import InpaintCrop
|
||||
from .inpaint_cropandstitch_old import InpaintStitch
|
||||
from .inpaint_cropandstitch_old import InpaintExtendOutpaint
|
||||
from .inpaint_cropandstitch_old import InpaintResize
|
||||
|
||||
WEB_DIRECTORY = "js"
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"InpaintCropImproved": InpaintCropImproved,
|
||||
"InpaintStitchImproved": InpaintStitchImproved,
|
||||
|
||||
# OLD
|
||||
"InpaintCrop": InpaintCrop,
|
||||
"InpaintStitch": InpaintStitch,
|
||||
"InpaintExtendOutpaint": InpaintExtendOutpaint,
|
||||
"InpaintResize": InpaintResize,
|
||||
}
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"InpaintCropImproved": "✂️ Inpaint Crop (Improved)",
|
||||
"InpaintStitchImproved": "✂️ Inpaint Stitch (Improved)",
|
||||
|
||||
# OLD
|
||||
"InpaintCrop": "(OLD 💀, use the new ✂️ Inpaint Crop node)",
|
||||
"InpaintStitch": "(OLD 💀, use the new ✂️ Inpaint Stitch node)",
|
||||
"InpaintExtendOutpaint": "(OLD 💀 use Crop instead) Extend Image for Outpainting",
|
||||
"InpaintResize": "(OLD 💀 use Crop instead) Resize Image Before Inpainting",
|
||||
"InpaintCropImproved": "✂️ Inpaint Crop",
|
||||
"InpaintStitchImproved": "✂️ Inpaint Stitch",
|
||||
}
|
||||
|
||||
__all__ = ['NODE_CLASS_MAPPINGS', 'NODE_DISPLAY_NAME_MAPPINGS']
|
||||
|
||||
+1240
-578
File diff suppressed because it is too large
Load Diff
@@ -1,887 +0,0 @@
|
||||
import comfy.utils
|
||||
import math
|
||||
import nodes
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchvision.transforms.functional as F
|
||||
from PIL import Image
|
||||
from scipy.ndimage import gaussian_filter, grey_dilation, binary_fill_holes, binary_closing
|
||||
|
||||
def rescale(samples, width, height, algorithm: str):
|
||||
if algorithm == "bislerp": # convert for compatibility with old workflows
|
||||
algorithm = "bicubic"
|
||||
algorithm = getattr(Image, algorithm.upper()) # i.e. Image.BICUBIC
|
||||
samples_pil: Image.Image = F.to_pil_image(samples[0].cpu()).resize((width, height), algorithm)
|
||||
samples = F.to_tensor(samples_pil).unsqueeze(0)
|
||||
return samples
|
||||
|
||||
class InpaintCrop:
|
||||
"""
|
||||
ComfyUI-InpaintCropAndStitch
|
||||
https://github.com/lquesada/ComfyUI-InpaintCropAndStitch
|
||||
|
||||
This node crop before sampling and stitch after sampling for fast, efficient inpainting without altering unmasked areas.
|
||||
Context area can be specified via expand pixels and expand factor or via a separate (optional) mask.
|
||||
Works free size, forced size, and ranged size.
|
||||
"""
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"mask": ("MASK",),
|
||||
"context_expand_pixels": ("INT", {"default": 20, "min": 0, "max": nodes.MAX_RESOLUTION, "step": 1}),
|
||||
"context_expand_factor": ("FLOAT", {"default": 1.0, "min": 1.0, "max": 100.0, "step": 0.01}),
|
||||
"fill_mask_holes": ("BOOLEAN", {"default": True}),
|
||||
"blur_mask_pixels": ("FLOAT", {"default": 16.0, "min": 0.0, "max": 256.0, "step": 0.1}),
|
||||
"invert_mask": ("BOOLEAN", {"default": False}),
|
||||
"blend_pixels": ("FLOAT", {"default": 16.0, "min": 0.0, "max": 32.0, "step": 0.1}),
|
||||
"rescale_algorithm": (["nearest", "bilinear", "bicubic", "bislerp", "lanczos", "box", "hamming"], {"default": "bicubic"}),
|
||||
"mode": (["ranged size", "forced size", "free size"], {"default": "ranged size"}),
|
||||
"force_width": ("INT", {"default": 1024, "min": 0, "max": nodes.MAX_RESOLUTION, "step": 1}), # force
|
||||
"force_height": ("INT", {"default": 1024, "min": 0, "max": nodes.MAX_RESOLUTION, "step": 1}), # force
|
||||
"rescale_factor": ("FLOAT", {"default": 1.00, "min": 0.01, "max": 100.0, "step": 0.01}), # free
|
||||
"min_width": ("INT", {"default": 512, "min": 0, "max": nodes.MAX_RESOLUTION, "step": 1}), # ranged
|
||||
"min_height": ("INT", {"default": 512, "min": 0, "max": nodes.MAX_RESOLUTION, "step": 1}), # ranged
|
||||
"max_width": ("INT", {"default": 768, "min": 0, "max": nodes.MAX_RESOLUTION, "step": 1}), # ranged
|
||||
"max_height": ("INT", {"default": 768, "min": 0, "max": nodes.MAX_RESOLUTION, "step": 1}), # ranged
|
||||
"padding": ([8, 16, 32, 64, 128, 256, 512], {"default": 32}), # free and ranged
|
||||
},
|
||||
"optional": {
|
||||
"optional_context_mask": ("MASK",),
|
||||
}
|
||||
}
|
||||
|
||||
CATEGORY = "inpaint"
|
||||
|
||||
RETURN_TYPES = ("STITCH", "IMAGE", "MASK")
|
||||
RETURN_NAMES = ("stitch", "cropped_image", "cropped_mask")
|
||||
|
||||
FUNCTION = "inpaint_crop"
|
||||
|
||||
def grow_and_blur_mask(self, mask, blur_pixels):
|
||||
if blur_pixels > 0.001:
|
||||
sigma = blur_pixels / 4
|
||||
growmask = mask.reshape((-1, mask.shape[-2], mask.shape[-1])).cpu()
|
||||
out = []
|
||||
for m in growmask:
|
||||
mask_np = m.numpy()
|
||||
kernel_size = math.ceil(sigma * 1.5 + 1)
|
||||
kernel = np.ones((kernel_size, kernel_size), dtype=np.uint8)
|
||||
dilated_mask = grey_dilation(mask_np, footprint=kernel)
|
||||
output = dilated_mask.astype(np.float32) * 255
|
||||
output = torch.from_numpy(output)
|
||||
out.append(output)
|
||||
mask = torch.stack(out, dim=0)
|
||||
mask = torch.clamp(mask, 0.0, 1.0)
|
||||
|
||||
mask_np = mask.numpy()
|
||||
filtered_mask = gaussian_filter(mask_np, sigma=sigma)
|
||||
mask = torch.from_numpy(filtered_mask)
|
||||
mask = torch.clamp(mask, 0.0, 1.0)
|
||||
|
||||
return mask
|
||||
|
||||
def adjust_to_aspect_ratio(self, x_min, x_max, y_min, y_max, width, height, target_width, target_height):
|
||||
x_min_key, x_max_key, y_min_key, y_max_key = x_min, x_max, y_min, y_max
|
||||
|
||||
# Calculate the current width and height
|
||||
current_width = x_max - x_min + 1
|
||||
current_height = y_max - y_min + 1
|
||||
|
||||
# Calculate aspect ratios
|
||||
aspect_ratio = target_width / target_height
|
||||
current_aspect_ratio = current_width / current_height
|
||||
|
||||
if current_aspect_ratio < aspect_ratio:
|
||||
# Adjust width to match target aspect ratio
|
||||
new_width = int(current_height * aspect_ratio)
|
||||
extend_x = (new_width - current_width)
|
||||
x_min = max(x_min - extend_x//2, 0)
|
||||
x_max = min(x_max + extend_x//2, width - 1)
|
||||
else:
|
||||
# Adjust height to match target aspect ratio
|
||||
new_height = int(current_width / aspect_ratio)
|
||||
extend_y = (new_height - current_height)
|
||||
y_min = max(y_min - extend_y//2, 0)
|
||||
y_max = min(y_max + extend_y//2, height - 1)
|
||||
|
||||
return int(x_min), int(x_max), int(y_min), int(y_max)
|
||||
|
||||
def adjust_to_preferred(self, x_min, x_max, y_min, y_max, width, height, preferred_x_start, preferred_x_end, preferred_y_start, preferred_y_end):
|
||||
# Ensure the area is within preferred bounds as much as possible
|
||||
if preferred_x_start <= x_min and preferred_x_end >= x_max and preferred_y_start <= y_min and preferred_y_end >= y_max:
|
||||
return x_min, x_max, y_min, y_max
|
||||
|
||||
# Shift x_min and x_max to fit within preferred bounds if possible
|
||||
if x_max - x_min + 1 <= preferred_x_end - preferred_x_start + 1:
|
||||
if x_min < preferred_x_start:
|
||||
x_shift = preferred_x_start - x_min
|
||||
x_min += x_shift
|
||||
x_max += x_shift
|
||||
elif x_max > preferred_x_end:
|
||||
x_shift = x_max - preferred_x_end
|
||||
x_min -= x_shift
|
||||
x_max -= x_shift
|
||||
|
||||
# Shift y_min and y_max to fit within preferred bounds if possible
|
||||
if y_max - y_min + 1 <= preferred_y_end - preferred_y_start + 1:
|
||||
if y_min < preferred_y_start:
|
||||
y_shift = preferred_y_start - y_min
|
||||
y_min += y_shift
|
||||
y_max += y_shift
|
||||
elif y_max > preferred_y_end:
|
||||
y_shift = y_max - preferred_y_end
|
||||
y_min -= y_shift
|
||||
y_max -= y_shift
|
||||
|
||||
return int(x_min), int(x_max), int(y_min), int(y_max)
|
||||
|
||||
def apply_padding(self, min_val, max_val, max_boundary, padding):
|
||||
# Calculate the midpoint and the original range size
|
||||
original_range_size = max_val - min_val + 1
|
||||
midpoint = (min_val + max_val) // 2
|
||||
|
||||
# Determine the smallest multiple of padding that is >= original_range_size
|
||||
if original_range_size % padding == 0:
|
||||
new_range_size = original_range_size
|
||||
else:
|
||||
new_range_size = (original_range_size // padding + 1) * padding
|
||||
|
||||
# Calculate the new min and max values centered on the midpoint
|
||||
new_min_val = max(midpoint - new_range_size // 2, 0)
|
||||
new_max_val = new_min_val + new_range_size - 1
|
||||
|
||||
# Ensure the new max doesn't exceed the boundary
|
||||
if new_max_val >= max_boundary:
|
||||
new_max_val = max_boundary - 1
|
||||
new_min_val = max(new_max_val - new_range_size + 1, 0)
|
||||
|
||||
# Ensure the range still ends on a multiple of padding
|
||||
# Adjust if the calculated range isn't feasible within the given constraints
|
||||
if (new_max_val - new_min_val + 1) != new_range_size:
|
||||
new_min_val = max(new_max_val - new_range_size + 1, 0)
|
||||
|
||||
return new_min_val, new_max_val
|
||||
|
||||
def inpaint_crop(self, image, mask, context_expand_pixels, context_expand_factor, fill_mask_holes, blur_mask_pixels, invert_mask, blend_pixels, mode, rescale_algorithm, force_width, force_height, rescale_factor, padding, min_width, min_height, max_width, max_height, optional_context_mask=None):
|
||||
if image.shape[0] > 1:
|
||||
assert mode == "forced size", "Mode must be 'forced size' when input is a batch of images"
|
||||
assert image.shape[0] == mask.shape[0], "Batch size of images and masks must be the same"
|
||||
if optional_context_mask is not None:
|
||||
assert optional_context_mask.shape[0] == image.shape[0], "Batch size of optional_context_masks must be the same as images or None"
|
||||
|
||||
result_stitch = {'x': [], 'y': [], 'original_image': [], 'cropped_mask_blend': [], 'rescale_x': [], 'rescale_y': [], 'start_x': [], 'start_y': [], 'initial_width': [], 'initial_height': []}
|
||||
results_image = []
|
||||
results_mask = []
|
||||
|
||||
batch_size = image.shape[0]
|
||||
for b in range(batch_size):
|
||||
one_image = image[b].unsqueeze(0)
|
||||
one_mask = mask[b].unsqueeze(0)
|
||||
one_optional_context_mask = None
|
||||
if optional_context_mask is not None:
|
||||
one_optional_context_mask = optional_context_mask[b].unsqueeze(0)
|
||||
|
||||
stitch, cropped_image, cropped_mask = self.inpaint_crop_single_image(one_image, one_mask, context_expand_pixels, context_expand_factor, fill_mask_holes, blur_mask_pixels, invert_mask, blend_pixels, mode, rescale_algorithm, force_width, force_height, rescale_factor, padding, min_width, min_height, max_width, max_height, one_optional_context_mask)
|
||||
|
||||
for key in result_stitch:
|
||||
result_stitch[key].append(stitch[key])
|
||||
cropped_image = cropped_image.squeeze(0)
|
||||
results_image.append(cropped_image)
|
||||
cropped_mask = cropped_mask.squeeze(0)
|
||||
results_mask.append(cropped_mask)
|
||||
|
||||
result_image = torch.stack(results_image, dim=0)
|
||||
result_mask = torch.stack(results_mask, dim=0)
|
||||
|
||||
return result_stitch, result_image, result_mask
|
||||
|
||||
# Parts of this function are from KJNodes: https://github.com/kijai/ComfyUI-KJNodes
|
||||
def inpaint_crop_single_image(self, image, mask, context_expand_pixels, context_expand_factor, fill_mask_holes, blur_mask_pixels, invert_mask, blend_pixels, mode, rescale_algorithm, force_width, force_height, rescale_factor, padding, min_width, min_height, max_width, max_height, optional_context_mask=None):
|
||||
#Validate or initialize mask
|
||||
if mask.shape[1] != image.shape[1] or mask.shape[2] != image.shape[2]:
|
||||
non_zero_indices = torch.nonzero(mask[0], as_tuple=True)
|
||||
if not non_zero_indices[0].size(0):
|
||||
mask = torch.zeros_like(image[:, :, :, 0])
|
||||
else:
|
||||
assert False, "mask size must match image size"
|
||||
|
||||
# Fill holes if requested
|
||||
if fill_mask_holes:
|
||||
holemask = mask.reshape((-1, mask.shape[-2], mask.shape[-1])).cpu()
|
||||
out = []
|
||||
for m in holemask:
|
||||
mask_np = m.numpy()
|
||||
binary_mask = mask_np > 0
|
||||
struct = np.ones((5, 5))
|
||||
closed_mask = binary_closing(binary_mask, structure=struct, border_value=1)
|
||||
filled_mask = binary_fill_holes(closed_mask)
|
||||
output = filled_mask.astype(np.float32) * 255
|
||||
output = torch.from_numpy(output)
|
||||
out.append(output)
|
||||
mask = torch.stack(out, dim=0)
|
||||
mask = torch.clamp(mask, 0.0, 1.0)
|
||||
|
||||
# Grow and blur mask if requested
|
||||
if blur_mask_pixels > 0.001:
|
||||
mask = self.grow_and_blur_mask(mask, blur_mask_pixels)
|
||||
|
||||
# Invert mask if requested
|
||||
if invert_mask:
|
||||
mask = 1.0 - mask
|
||||
|
||||
# Validate or initialize context mask
|
||||
if optional_context_mask is None:
|
||||
context_mask = mask
|
||||
elif optional_context_mask.shape[1] != image.shape[1] or optional_context_mask.shape[2] != image.shape[2]:
|
||||
non_zero_indices = torch.nonzero(optional_context_mask[0], as_tuple=True)
|
||||
if not non_zero_indices[0].size(0):
|
||||
context_mask = mask
|
||||
else:
|
||||
assert False, "context_mask size must match image size"
|
||||
else:
|
||||
context_mask = optional_context_mask + mask
|
||||
context_mask = torch.clamp(context_mask, 0.0, 1.0)
|
||||
|
||||
# Ensure mask dimensions match image dimensions except channels
|
||||
initial_batch, initial_height, initial_width, initial_channels = image.shape
|
||||
mask_batch, mask_height, mask_width = mask.shape
|
||||
context_mask_batch, context_mask_height, context_mask_width = context_mask.shape
|
||||
assert initial_height == mask_height and initial_width == mask_width, "Image and mask dimensions must match"
|
||||
assert initial_height == context_mask_height and initial_width == context_mask_width, "Image and context mask dimensions must match"
|
||||
|
||||
# Extend image and masks to turn it into a big square in case the context area would go off bounds
|
||||
extend_y = (initial_width + 1) // 2 # Intended, extend height by width (turn into square)
|
||||
extend_x = (initial_height + 1) // 2 # Intended, extend width by height (turn into square)
|
||||
new_height = initial_height + 2 * extend_y
|
||||
new_width = initial_width + 2 * extend_x
|
||||
|
||||
start_y = extend_y
|
||||
start_x = extend_x
|
||||
|
||||
available_top = min(start_y, initial_height)
|
||||
available_bottom = min(new_height - (start_y + initial_height), initial_height)
|
||||
available_left = min(start_x, initial_width)
|
||||
available_right = min(new_width - (start_x + initial_width), initial_width)
|
||||
|
||||
new_image = torch.zeros((initial_batch, new_height, new_width, initial_channels), dtype=image.dtype)
|
||||
new_image[:, start_y:start_y + initial_height, start_x:start_x + initial_width, :] = image
|
||||
# Mirror image so there's no bleeding of black border when using inpaintmodelconditioning
|
||||
# Top
|
||||
new_image[:, start_y - available_top:start_y, start_x:start_x + initial_width, :] = torch.flip(image[:, :available_top, :, :], [1])
|
||||
# Bottom
|
||||
new_image[:, start_y + initial_height:start_y + initial_height + available_bottom, start_x:start_x + initial_width, :] = torch.flip(image[:, -available_bottom:, :, :], [1])
|
||||
# Left
|
||||
new_image[:, start_y:start_y + initial_height, start_x - available_left:start_x, :] = torch.flip(new_image[:, start_y:start_y + initial_height, start_x:start_x + available_left, :], [2])
|
||||
# Right
|
||||
new_image[:, start_y:start_y + initial_height, start_x + initial_width:start_x + initial_width + available_right, :] = torch.flip(new_image[:, start_y:start_y + initial_height, start_x + initial_width - available_right:start_x + initial_width, :], [2])
|
||||
# Top-left corner
|
||||
new_image[:, start_y - available_top:start_y, start_x - available_left:start_x, :] = torch.flip(new_image[:, start_y:start_y + available_top, start_x:start_x + available_left, :], [1, 2])
|
||||
# Top-right corner
|
||||
new_image[:, start_y - available_top:start_y, start_x + initial_width:start_x + initial_width + available_right, :] = torch.flip(new_image[:, start_y:start_y + available_top, start_x + initial_width - available_right:start_x + initial_width, :], [1, 2])
|
||||
# Bottom-left corner
|
||||
new_image[:, start_y + initial_height:start_y + initial_height + available_bottom, start_x - available_left:start_x, :] = torch.flip(new_image[:, start_y + initial_height - available_bottom:start_y + initial_height, start_x:start_x + available_left, :], [1, 2])
|
||||
# Bottom-right corner
|
||||
new_image[:, start_y + initial_height:start_y + initial_height + available_bottom, start_x + initial_width:start_x + initial_width + available_right, :] = torch.flip(new_image[:, start_y + initial_height - available_bottom:start_y + initial_height, start_x + initial_width - available_right:start_x + initial_width, :], [1, 2])
|
||||
|
||||
new_mask = torch.ones((mask_batch, new_height, new_width), dtype=mask.dtype) # assume ones in extended image
|
||||
new_mask[:, start_y:start_y + initial_height, start_x:start_x + initial_width] = mask
|
||||
|
||||
blend_mask = torch.zeros((mask_batch, new_height, new_width), dtype=mask.dtype) # assume zeros in extended image
|
||||
blend_mask[:, start_y:start_y + initial_height, start_x:start_x + initial_width] = mask
|
||||
# Mirror blend mask so there's no bleeding of border when blending
|
||||
# Top
|
||||
blend_mask[:, start_y - available_top:start_y, start_x:start_x + initial_width] = torch.flip(mask[:, :available_top, :], [1])
|
||||
# Bottom
|
||||
blend_mask[:, start_y + initial_height:start_y + initial_height + available_bottom, start_x:start_x + initial_width] = torch.flip(mask[:, -available_bottom:, :], [1])
|
||||
# Left
|
||||
blend_mask[:, start_y:start_y + initial_height, start_x - available_left:start_x] = torch.flip(blend_mask[:, start_y:start_y + initial_height, start_x:start_x + available_left], [2])
|
||||
# Right
|
||||
blend_mask[:, start_y:start_y + initial_height, start_x + initial_width:start_x + initial_width + available_right] = torch.flip(blend_mask[:, start_y:start_y + initial_height, start_x + initial_width - available_right:start_x + initial_width], [2])
|
||||
# Top-left corner
|
||||
blend_mask[:, start_y - available_top:start_y, start_x - available_left:start_x] = torch.flip(blend_mask[:, start_y:start_y + available_top, start_x:start_x + available_left], [1, 2])
|
||||
# Top-right corner
|
||||
blend_mask[:, start_y - available_top:start_y, start_x + initial_width:start_x + initial_width + available_right] = torch.flip(blend_mask[:, start_y:start_y + available_top, start_x + initial_width - available_right:start_x + initial_width], [1, 2])
|
||||
# Bottom-left corner
|
||||
blend_mask[:, start_y + initial_height:start_y + initial_height + available_bottom, start_x - available_left:start_x] = torch.flip(blend_mask[:, start_y + initial_height - available_bottom:start_y + initial_height, start_x:start_x + available_left], [1, 2])
|
||||
# Bottom-right corner
|
||||
blend_mask[:, start_y + initial_height:start_y + initial_height + available_bottom, start_x + initial_width:start_x + initial_width + available_right] = torch.flip(blend_mask[:, start_y + initial_height - available_bottom:start_y + initial_height, start_x + initial_width - available_right:start_x + initial_width], [1, 2])
|
||||
|
||||
new_context_mask = torch.zeros((mask_batch, new_height, new_width), dtype=context_mask.dtype)
|
||||
new_context_mask[:, start_y:start_y + initial_height, start_x:start_x + initial_width] = context_mask
|
||||
|
||||
image = new_image
|
||||
mask = new_mask
|
||||
context_mask = new_context_mask
|
||||
|
||||
original_image = image
|
||||
original_mask = mask
|
||||
original_width = image.shape[2]
|
||||
original_height = image.shape[1]
|
||||
|
||||
# If there are no non-zero indices in the context_mask, adjust context mask to the whole image
|
||||
non_zero_indices = torch.nonzero(context_mask[0], as_tuple=True)
|
||||
if not non_zero_indices[0].size(0):
|
||||
context_mask = torch.ones_like(image[:, :, :, 0])
|
||||
context_mask = torch.zeros((mask_batch, new_height, new_width), dtype=mask.dtype)
|
||||
context_mask[:, start_y:start_y + initial_height, start_x:start_x + initial_width] += 1.0
|
||||
non_zero_indices = torch.nonzero(context_mask[0], as_tuple=True)
|
||||
|
||||
# Compute context area from context mask
|
||||
y_min = torch.min(non_zero_indices[0]).item()
|
||||
y_max = torch.max(non_zero_indices[0]).item()
|
||||
x_min = torch.min(non_zero_indices[1]).item()
|
||||
x_max = torch.max(non_zero_indices[1]).item()
|
||||
height = context_mask.shape[1]
|
||||
width = context_mask.shape[2]
|
||||
|
||||
# Grow context area if requested
|
||||
y_size = y_max - y_min + 1
|
||||
x_size = x_max - x_min + 1
|
||||
y_grow = round(max(y_size*(context_expand_factor-1), context_expand_pixels, blend_pixels**1.5))
|
||||
x_grow = round(max(x_size*(context_expand_factor-1), context_expand_pixels, blend_pixels**1.5))
|
||||
y_min = max(y_min - y_grow // 2, 0)
|
||||
y_max = min(y_max + y_grow // 2, height - 1)
|
||||
x_min = max(x_min - x_grow // 2, 0)
|
||||
x_max = min(x_max + x_grow // 2, width - 1)
|
||||
y_size = y_max - y_min + 1
|
||||
x_size = x_max - x_min + 1
|
||||
|
||||
effective_upscale_factor_x = 1.0
|
||||
effective_upscale_factor_y = 1.0
|
||||
|
||||
# Adjust to preferred size
|
||||
if mode == 'forced size':
|
||||
#Sub case of ranged size.
|
||||
min_width = max_width = force_width
|
||||
min_height = max_height = force_height
|
||||
|
||||
if mode == 'ranged size' or mode == 'forced size':
|
||||
assert max_width >= min_width, "max_width must be greater than or equal to min_width"
|
||||
assert max_height >= min_height, "max_height must be greater than or equal to min_height"
|
||||
# Ensure we set an aspect ratio supported by min_width, max_width, min_height, max_height
|
||||
current_width = x_max - x_min + 1
|
||||
current_height = y_max - y_min + 1
|
||||
|
||||
# Calculate aspect ratio of the selected area
|
||||
current_aspect_ratio = current_width / current_height
|
||||
|
||||
# Calculate the aspect ratio bounds
|
||||
min_aspect_ratio = min_width / max_height
|
||||
max_aspect_ratio = max_width / min_height
|
||||
|
||||
# Adjust target width and height based on aspect ratio bounds
|
||||
if current_aspect_ratio < min_aspect_ratio:
|
||||
# Adjust to meet minimum width constraint
|
||||
target_width = min(current_width, min_width)
|
||||
target_height = int(target_width / min_aspect_ratio)
|
||||
x_min, x_max, y_min, y_max = self.adjust_to_aspect_ratio(x_min, x_max, y_min, y_max, width, height, target_width, target_height)
|
||||
x_min, x_max, y_min, y_max = self.adjust_to_preferred(x_min, x_max, y_min, y_max, width, height, start_x, start_x+initial_width, start_y, start_y+initial_height)
|
||||
elif current_aspect_ratio > max_aspect_ratio:
|
||||
# Adjust to meet maximum width constraint
|
||||
target_height = min(current_height, max_height)
|
||||
target_width = int(target_height * max_aspect_ratio)
|
||||
x_min, x_max, y_min, y_max = self.adjust_to_aspect_ratio(x_min, x_max, y_min, y_max, width, height, target_width, target_height)
|
||||
x_min, x_max, y_min, y_max = self.adjust_to_preferred(x_min, x_max, y_min, y_max, width, height, start_x, start_x+initial_width, start_y, start_y+initial_height)
|
||||
else:
|
||||
# Aspect ratio is within bounds, keep the current size
|
||||
target_width = current_width
|
||||
target_height = current_height
|
||||
|
||||
y_size = y_max - y_min + 1
|
||||
x_size = x_max - x_min + 1
|
||||
|
||||
# Adjust to min and max sizes
|
||||
max_rescale_width = max_width / x_size
|
||||
max_rescale_height = max_height / y_size
|
||||
max_rescale_factor = min(max_rescale_width, max_rescale_height)
|
||||
rescale_factor = max_rescale_factor
|
||||
min_rescale_width = min_width / x_size
|
||||
min_rescale_height = min_height / y_size
|
||||
min_rescale_factor = min(min_rescale_width, min_rescale_height)
|
||||
rescale_factor = max(min_rescale_factor, rescale_factor)
|
||||
|
||||
# Upscale image and masks if requested, they will be downsized at stitch phase
|
||||
if rescale_factor < 0.999 or rescale_factor > 1.001:
|
||||
samples = image
|
||||
samples = samples.movedim(-1, 1)
|
||||
width = round(samples.shape[3] * rescale_factor)
|
||||
height = round(samples.shape[2] * rescale_factor)
|
||||
samples = rescale(samples, width, height, rescale_algorithm)
|
||||
effective_upscale_factor_x = float(width)/float(original_width)
|
||||
effective_upscale_factor_y = float(height)/float(original_height)
|
||||
samples = samples.movedim(1, -1)
|
||||
image = samples
|
||||
|
||||
samples = mask
|
||||
samples = samples.unsqueeze(1)
|
||||
samples = rescale(samples, width, height, "nearest")
|
||||
samples = samples.squeeze(1)
|
||||
mask = samples
|
||||
|
||||
samples = blend_mask
|
||||
samples = samples.unsqueeze(1)
|
||||
samples = rescale(samples, width, height, "nearest")
|
||||
samples = samples.squeeze(1)
|
||||
blend_mask = samples
|
||||
|
||||
# Do math based on min,size instead of min,max to avoid rounding errors
|
||||
y_size = y_max - y_min + 1
|
||||
x_size = x_max - x_min + 1
|
||||
target_x_size = int(x_size * effective_upscale_factor_x)
|
||||
target_y_size = int(y_size * effective_upscale_factor_y)
|
||||
|
||||
x_min = round(x_min * effective_upscale_factor_x)
|
||||
x_max = x_min + target_x_size
|
||||
y_min = round(y_min * effective_upscale_factor_y)
|
||||
y_max = y_min + target_y_size
|
||||
|
||||
x_size = x_max - x_min + 1
|
||||
y_size = y_max - y_min + 1
|
||||
|
||||
# Ensure width and height are within specified bounds, key for ranged and forced size
|
||||
if mode == 'ranged size' or mode == 'forced size':
|
||||
if x_size < min_width:
|
||||
x_max = min(x_max + (min_width - x_size), width - 1)
|
||||
elif x_size > max_width:
|
||||
x_max = x_min + max_width - 1
|
||||
|
||||
if y_size < min_height:
|
||||
y_max = min(y_max + (min_height - y_size), height - 1)
|
||||
elif y_size > max_height:
|
||||
y_max = y_min + max_height - 1
|
||||
|
||||
# Recalculate x_size and y_size after adjustments
|
||||
x_size = x_max - x_min + 1
|
||||
y_size = y_max - y_min + 1
|
||||
|
||||
# Pad area (if possible, i.e. if pad is smaller than width/height) to avoid the sampler returning smaller results
|
||||
if (mode == 'free size' or mode == 'ranged size') and padding > 1:
|
||||
x_min, x_max = self.apply_padding(x_min, x_max, width, padding)
|
||||
y_min, y_max = self.apply_padding(y_min, y_max, height, padding)
|
||||
|
||||
# Ensure that context area doesn't go outside of the image
|
||||
x_min = max(x_min, 0)
|
||||
x_max = min(x_max, width - 1)
|
||||
y_min = max(y_min, 0)
|
||||
y_max = min(y_max, height - 1)
|
||||
|
||||
# Crop the image and the mask, sized context area
|
||||
cropped_image = image[:, y_min:y_max+1, x_min:x_max+1]
|
||||
cropped_mask = mask[:, y_min:y_max+1, x_min:x_max+1]
|
||||
cropped_mask_blend = blend_mask[:, y_min:y_max+1, x_min:x_max+1]
|
||||
|
||||
# Grow and blur mask for blend if requested
|
||||
if blend_pixels > 0.001:
|
||||
cropped_mask_blend = self.grow_and_blur_mask(cropped_mask_blend, blend_pixels)
|
||||
|
||||
# Return stitch (to be consumed by the class below), image, and mask
|
||||
stitch = {'x': x_min, 'y': y_min, 'original_image': original_image, 'cropped_mask_blend': cropped_mask_blend, 'rescale_x': effective_upscale_factor_x, 'rescale_y': effective_upscale_factor_y, 'start_x': start_x, 'start_y': start_y, 'initial_width': initial_width, 'initial_height': initial_height}
|
||||
|
||||
return (stitch, cropped_image, cropped_mask)
|
||||
|
||||
|
||||
class InpaintStitch:
|
||||
"""
|
||||
ComfyUI-InpaintCropAndStitch
|
||||
https://github.com/lquesada/ComfyUI-InpaintCropAndStitch
|
||||
|
||||
This node stitches the inpainted image without altering unmasked areas.
|
||||
"""
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"stitch": ("STITCH",),
|
||||
"inpainted_image": ("IMAGE",),
|
||||
"rescale_algorithm": (["nearest", "bilinear", "bicubic", "bislerp", "lanczos", "box", "hamming"], {"default": "bislerp"}),
|
||||
}
|
||||
}
|
||||
|
||||
CATEGORY = "inpaint"
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES = ("image",)
|
||||
|
||||
FUNCTION = "inpaint_stitch"
|
||||
|
||||
# This function is from comfy_extras: https://github.com/comfyanonymous/ComfyUI
|
||||
def composite(self, destination, source, x, y, mask=None, multiplier=8, resize_source=False):
|
||||
source = source.to(destination.device)
|
||||
if resize_source:
|
||||
source = torch.nn.functional.interpolate(source, size=(destination.shape[2], destination.shape[3]), mode="bilinear")
|
||||
|
||||
source = comfy.utils.repeat_to_batch_size(source, destination.shape[0])
|
||||
|
||||
x = max(-source.shape[3] * multiplier, min(x, destination.shape[3] * multiplier))
|
||||
y = max(-source.shape[2] * multiplier, min(y, destination.shape[2] * multiplier))
|
||||
|
||||
left, top = (x // multiplier, y // multiplier)
|
||||
right, bottom = (left + source.shape[3], top + source.shape[2],)
|
||||
|
||||
if mask is None:
|
||||
mask = torch.ones_like(source)
|
||||
else:
|
||||
mask = mask.to(destination.device, copy=True)
|
||||
mask = torch.nn.functional.interpolate(mask.reshape((-1, 1, mask.shape[-2], mask.shape[-1])), size=(source.shape[2], source.shape[3]), mode="bilinear")
|
||||
mask = comfy.utils.repeat_to_batch_size(mask, source.shape[0])
|
||||
|
||||
# calculate the bounds of the source that will be overlapping the destination
|
||||
# this prevents the source trying to overwrite latent pixels that are out of bounds
|
||||
# of the destination
|
||||
visible_width, visible_height = (destination.shape[3] - left + min(0, x), destination.shape[2] - top + min(0, y),)
|
||||
|
||||
mask = mask[:, :, :visible_height, :visible_width]
|
||||
inverse_mask = torch.ones_like(mask) - mask
|
||||
|
||||
source_portion = mask * source[:, :, :visible_height, :visible_width]
|
||||
destination_portion = inverse_mask * destination[:, :, top:bottom, left:right]
|
||||
|
||||
destination[:, :, top:bottom, left:right] = source_portion + destination_portion
|
||||
return destination
|
||||
|
||||
def inpaint_stitch(self, stitch, inpainted_image, rescale_algorithm):
|
||||
results = []
|
||||
|
||||
batch_size = inpainted_image.shape[0]
|
||||
assert len(stitch['x']) == batch_size, "Stitch size doesn't match image batch size"
|
||||
for b in range(batch_size):
|
||||
one_image = inpainted_image[b]
|
||||
one_stitch = {}
|
||||
for key in stitch:
|
||||
# Extract the value at the specified index and assign it to the single_stitch dictionary
|
||||
one_stitch[key] = stitch[key][b]
|
||||
one_image = one_image.unsqueeze(0)
|
||||
one_image, = self.inpaint_stitch_single_image(one_stitch, one_image, rescale_algorithm)
|
||||
one_image = one_image.squeeze(0)
|
||||
results.append(one_image)
|
||||
|
||||
# Stack the results to form a batch
|
||||
result_batch = torch.stack(results, dim=0)
|
||||
|
||||
return (result_batch,)
|
||||
|
||||
def inpaint_stitch_single_image(self, stitch, inpainted_image, rescale_algorithm):
|
||||
original_image = stitch['original_image']
|
||||
cropped_mask_blend = stitch['cropped_mask_blend']
|
||||
x = stitch['x']
|
||||
y = stitch['y']
|
||||
stitched_image = original_image.clone().movedim(-1, 1)
|
||||
start_x = stitch['start_x']
|
||||
start_y = stitch['start_y']
|
||||
initial_width = stitch['initial_width']
|
||||
initial_height = stitch['initial_height']
|
||||
|
||||
inpaint_width = inpainted_image.shape[2]
|
||||
inpaint_height = inpainted_image.shape[1]
|
||||
|
||||
# Downscale inpainted before stitching if we upscaled it before
|
||||
if stitch['rescale_x'] < 0.999 or stitch['rescale_x'] > 1.001 or stitch['rescale_y'] < 0.999 or stitch['rescale_y'] > 1.001:
|
||||
samples = inpainted_image.movedim(-1, 1)
|
||||
|
||||
width = math.ceil(float(inpaint_width)/stitch['rescale_x'])+1
|
||||
height = math.ceil(float(inpaint_height)/stitch['rescale_y'])+1
|
||||
x = math.floor(float(x)/stitch['rescale_x'])
|
||||
y = math.floor(float(y)/stitch['rescale_y'])
|
||||
|
||||
samples = rescale(samples, width, height, rescale_algorithm)
|
||||
inpainted_image = samples.movedim(1, -1)
|
||||
|
||||
samples = cropped_mask_blend.movedim(-1, 1)
|
||||
samples = samples.unsqueeze(0)
|
||||
samples = rescale(samples, width, height, rescale_algorithm)
|
||||
samples = samples.squeeze(0)
|
||||
cropped_mask_blend = samples.movedim(1, -1)
|
||||
cropped_mask_blend = torch.clamp(cropped_mask_blend, 0.0, 1.0)
|
||||
|
||||
output = self.composite(stitched_image, inpainted_image.movedim(-1, 1), x, y, cropped_mask_blend, 1).movedim(1, -1)
|
||||
|
||||
# Crop out from the extended dimensions back to original.
|
||||
cropped_output = output[:, start_y:start_y + initial_height, start_x:start_x + initial_width, :]
|
||||
output = cropped_output
|
||||
return (output,)
|
||||
|
||||
|
||||
class InpaintExtendOutpaint:
|
||||
"""
|
||||
ComfyUI-InpaintCropAndStitch
|
||||
https://github.com/lquesada/ComfyUI-InpaintCropAndStitch
|
||||
|
||||
This node extends an image for inpainting with Inpaint Crop and Stitch.
|
||||
"""
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"mask": ("MASK",),
|
||||
"mode": (["factors", "pixels"], {"default": "factors"}),
|
||||
"expand_up_pixels": ("INT", {"default": 0, "min": 0, "max": nodes.MAX_RESOLUTION, "step": 1}),
|
||||
"expand_up_factor": ("FLOAT", {"default": 1.0, "min": 1.0, "max": 100.0, "step": 0.01}),
|
||||
"expand_down_pixels": ("INT", {"default": 0, "min": 0, "max": nodes.MAX_RESOLUTION, "step": 1}),
|
||||
"expand_down_factor": ("FLOAT", {"default": 1.0, "min": 1.0, "max": 100.0, "step": 0.01}),
|
||||
"expand_left_pixels": ("INT", {"default": 0, "min": 0, "max": nodes.MAX_RESOLUTION, "step": 1}),
|
||||
"expand_left_factor": ("FLOAT", {"default": 1.0, "min": 1.0, "max": 100.0, "step": 0.01}),
|
||||
"expand_right_pixels": ("INT", {"default": 0, "min": 0, "max": nodes.MAX_RESOLUTION, "step": 1}),
|
||||
"expand_right_factor": ("FLOAT", {"default": 1.0, "min": 1.0, "max": 100.0, "step": 0.01}),
|
||||
},
|
||||
"optional": {
|
||||
"optional_context_mask": ("MASK",),
|
||||
}
|
||||
}
|
||||
|
||||
CATEGORY = "inpaint"
|
||||
|
||||
RETURN_TYPES = ("IMAGE", "MASK", "MASK")
|
||||
RETURN_NAMES = ("image", "mask", "context_mask")
|
||||
|
||||
FUNCTION = "inpaint_extend"
|
||||
|
||||
def inpaint_extend(self, image, mask, mode, expand_up_pixels, expand_up_factor, expand_down_pixels, expand_down_factor, expand_left_pixels, expand_left_factor, expand_right_pixels, expand_right_factor, optional_context_mask=None):
|
||||
assert image.shape[0] == mask.shape[0], "Batch size of images and masks must be the same"
|
||||
if optional_context_mask is not None:
|
||||
assert optional_context_mask.shape[0] == image.shape[0], "Batch size of optional_context_masks must be the same as images or None"
|
||||
|
||||
results_image = []
|
||||
results_mask = []
|
||||
results_context_mask = []
|
||||
|
||||
batch_size = image.shape[0]
|
||||
for b in range(batch_size):
|
||||
one_image = image[b].unsqueeze(0) # Adding batch dimension
|
||||
one_mask = mask[b].unsqueeze(0) # Adding batch dimension
|
||||
one_context_mask = None
|
||||
if optional_context_mask is not None:
|
||||
one_context_mask = optional_context_mask[b].unsqueeze(0)
|
||||
|
||||
#Validate or initialize mask
|
||||
if one_mask.shape[1] != one_image.shape[1] or one_mask.shape[2] != one_image.shape[2]:
|
||||
non_zero_indices = torch.nonzero(one_mask[0], as_tuple=True)
|
||||
if not non_zero_indices[0].size(0):
|
||||
one_mask = torch.zeros_like(one_image[:, :, :, 0])
|
||||
else:
|
||||
assert False, "mask size must match image size"
|
||||
|
||||
# Validate or initialize context mask
|
||||
if one_context_mask is not None and (one_context_mask.shape[1] != one_image.shape[1] or one_context_mask.shape[2] != one_image.shape[2]):
|
||||
non_zero_indices = torch.nonzero(one_context_mask[0], as_tuple=True)
|
||||
if not non_zero_indices[0].size(0):
|
||||
one_context_mask = torch.zeros_like(one_image[:, :, :, 0])
|
||||
else:
|
||||
assert False, "context_mask size must match image size"
|
||||
|
||||
# Get original dimensions
|
||||
orig_height, orig_width = one_image.shape[1], one_image.shape[2]
|
||||
|
||||
if mode == "factors":
|
||||
# Calculate new dimensions based on factors
|
||||
new_height = int(orig_height * (expand_up_factor + expand_down_factor - 1))
|
||||
new_width = int(orig_width * (expand_left_factor + expand_right_factor - 1))
|
||||
|
||||
up_padding = int(orig_height * (expand_up_factor - 1))
|
||||
down_padding = new_height - orig_height - up_padding
|
||||
left_padding = int(orig_width * (expand_left_factor - 1))
|
||||
right_padding = new_width - orig_width - left_padding
|
||||
elif mode == "pixels":
|
||||
# Calculate new dimensions based on pixel expansion
|
||||
new_height = orig_height + expand_up_pixels + expand_down_pixels
|
||||
new_width = orig_width + expand_left_pixels + expand_right_pixels
|
||||
|
||||
up_padding = expand_up_pixels
|
||||
down_padding = expand_down_pixels
|
||||
left_padding = expand_left_pixels
|
||||
right_padding = expand_right_pixels
|
||||
|
||||
# Expand image
|
||||
new_image = torch.zeros((one_image.shape[0], new_height, new_width, one_image.shape[3]), dtype=one_image.dtype)
|
||||
new_image[:, up_padding:up_padding + orig_height, left_padding:left_padding + orig_width, :] = one_image.squeeze(0)
|
||||
|
||||
start_y = up_padding
|
||||
start_x = left_padding
|
||||
initial_height = orig_height
|
||||
initial_width = orig_width
|
||||
|
||||
# Mirror image so there's no bleeding of black border when using inpaintmodelconditioning
|
||||
available_top = min(start_y, initial_height)
|
||||
available_bottom = min(new_height - (start_y + initial_height), initial_height)
|
||||
available_left = min(start_x, initial_width)
|
||||
available_right = min(new_width - (start_x + initial_width), initial_width)
|
||||
# Top
|
||||
if available_top:
|
||||
new_image[:, start_y - available_top:start_y, start_x:start_x + initial_width, :] = torch.flip(image[:, :available_top, :, :], [1])
|
||||
# Bottom
|
||||
if available_bottom:
|
||||
new_image[:, start_y + initial_height:start_y + initial_height + available_bottom, start_x:start_x + initial_width, :] = torch.flip(image[:, -available_bottom:, :, :], [1])
|
||||
# Left
|
||||
if available_left:
|
||||
new_image[:, start_y:start_y + initial_height, start_x - available_left:start_x, :] = torch.flip(new_image[:, start_y:start_y + initial_height, start_x:start_x + available_left, :], [2])
|
||||
# Right
|
||||
if available_right:
|
||||
new_image[:, start_y:start_y + initial_height, start_x + initial_width:start_x + initial_width + available_right, :] = torch.flip(new_image[:, start_y:start_y + initial_height, start_x + initial_width - available_right:start_x + initial_width, :], [2])
|
||||
# Top-left corner
|
||||
if available_top and available_left:
|
||||
new_image[:, start_y - available_top:start_y, start_x - available_left:start_x, :] = torch.flip(new_image[:, start_y:start_y + available_top, start_x:start_x + available_left, :], [1, 2])
|
||||
# Top-right corner
|
||||
if available_top and available_right:
|
||||
new_image[:, start_y - available_top:start_y, start_x + initial_width:start_x + initial_width + available_right, :] = torch.flip(new_image[:, start_y:start_y + available_top, start_x + initial_width - available_right:start_x + initial_width, :], [1, 2])
|
||||
# Bottom-left corner
|
||||
if available_bottom and available_left:
|
||||
new_image[:, start_y + initial_height:start_y + initial_height + available_bottom, start_x - available_left:start_x, :] = torch.flip(new_image[:, start_y + initial_height - available_bottom:start_y + initial_height, start_x:start_x + available_left, :], [1, 2])
|
||||
# Bottom-right corner
|
||||
if available_bottom and available_right:
|
||||
new_image[:, start_y + initial_height:start_y + initial_height + available_bottom, start_x + initial_width:start_x + initial_width + available_right, :] = torch.flip(new_image[:, start_y + initial_height - available_bottom:start_y + initial_height, start_x + initial_width - available_right:start_x + initial_width, :], [1, 2])
|
||||
|
||||
|
||||
# Expand mask
|
||||
new_mask = torch.ones((one_mask.shape[0], new_height, new_width), dtype=one_mask.dtype)
|
||||
new_mask[:, up_padding:up_padding + orig_height, left_padding:left_padding + orig_width] = one_mask.squeeze(0)
|
||||
|
||||
# Expand context mask if present
|
||||
if one_context_mask is not None:
|
||||
new_context_mask = torch.zeros((one_context_mask.shape[0], new_height, new_width), dtype=one_context_mask.dtype)
|
||||
new_context_mask[:, up_padding:up_padding + orig_height, left_padding:left_padding + orig_width] = one_context_mask.squeeze(0)
|
||||
|
||||
# Append results
|
||||
results_image.append(new_image.squeeze(0))
|
||||
results_mask.append(new_mask.squeeze(0))
|
||||
if one_context_mask is not None:
|
||||
results_context_mask.append(new_context_mask.squeeze(0))
|
||||
|
||||
# Stack the results to form batches
|
||||
output_image = torch.stack(results_image, dim=0)
|
||||
output_mask = torch.stack(results_mask, dim=0)
|
||||
output_context_mask = None
|
||||
if optional_context_mask is not None:
|
||||
output_context_mask = torch.stack(results_context_mask, dim=0)
|
||||
|
||||
return (output_image, output_mask, output_context_mask)
|
||||
|
||||
|
||||
class InpaintResize:
|
||||
"""
|
||||
ComfyUI-InpaintCropAndStitch
|
||||
https://github.com/lquesada/ComfyUI-InpaintCropAndStitch
|
||||
|
||||
This node resizes an image before inpainting with Inpaint Crop and Stitch.
|
||||
"""
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"mask": ("MASK",),
|
||||
"rescale_algorithm": (["nearest", "bilinear", "bicubic", "bislerp", "lanczos", "box", "hamming"], {"default": "bicubic"}),
|
||||
"mode": (["ensure minimum size", "factor"], {"default": "ensure minimum size"}),
|
||||
"min_width": ("INT", {"default": 1024, "min": 0, "max": nodes.MAX_RESOLUTION, "step": 1}), # ranged
|
||||
"min_height": ("INT", {"default": 1024, "min": 0, "max": nodes.MAX_RESOLUTION, "step": 1}), # ranged
|
||||
"rescale_factor": ("FLOAT", {"default": 1.00, "min": 0.01, "max": 100.0, "step": 0.01}), # free
|
||||
},
|
||||
"optional": {
|
||||
"optional_context_mask": ("MASK",),
|
||||
}
|
||||
}
|
||||
|
||||
CATEGORY = "inpaint"
|
||||
|
||||
RETURN_TYPES = ("IMAGE", "MASK", "MASK")
|
||||
RETURN_NAMES = ("image", "mask", "context_mask")
|
||||
|
||||
FUNCTION = "inpaint_resize"
|
||||
|
||||
def inpaint_resize(self, image, mask, rescale_algorithm, mode, min_width, min_height, rescale_factor, optional_context_mask=None):
|
||||
assert image.shape[0] == mask.shape[0], "Batch size of images and masks must be the same"
|
||||
if optional_context_mask is not None:
|
||||
assert optional_context_mask.shape[0] == image.shape[0], "Batch size of optional_context_masks must be the same as images or None"
|
||||
|
||||
results_image = []
|
||||
results_mask = []
|
||||
results_context_mask = []
|
||||
|
||||
batch_size = image.shape[0]
|
||||
for b in range(batch_size):
|
||||
one_image = image[b].unsqueeze(0) # Adding batch dimension
|
||||
one_mask = mask[b].unsqueeze(0) # Adding batch dimension
|
||||
one_context_mask = None
|
||||
if optional_context_mask is not None:
|
||||
one_context_mask = optional_context_mask[b].unsqueeze(0)
|
||||
|
||||
#Validate or initialize mask
|
||||
if one_mask.shape[1] != one_image.shape[1] or one_mask.shape[2] != one_image.shape[2]:
|
||||
non_zero_indices = torch.nonzero(one_mask[0], as_tuple=True)
|
||||
if not non_zero_indices[0].size(0):
|
||||
one_mask = torch.zeros_like(one_image[:, :, :, 0])
|
||||
else:
|
||||
assert False, "mask size must match image size"
|
||||
|
||||
# Validate or initialize context mask
|
||||
if one_context_mask is not None and (one_context_mask.shape[1] != one_image.shape[1] or one_context_mask.shape[2] != one_image.shape[2]):
|
||||
non_zero_indices = torch.nonzero(one_context_mask[0], as_tuple=True)
|
||||
if not non_zero_indices[0].size(0):
|
||||
one_context_mask = torch.zeros_like(one_image[:, :, :, 0])
|
||||
else:
|
||||
assert False, "context_mask size must match image size"
|
||||
|
||||
# Get original dimensions
|
||||
orig_height, orig_width = one_image.shape[1], one_image.shape[2]
|
||||
|
||||
# Calculate target width and height
|
||||
if mode == "ensure minimum size":
|
||||
# Start with original dimensions
|
||||
width = orig_width
|
||||
height = orig_height
|
||||
|
||||
# If either dimension is smaller than the minimum, scale up
|
||||
if orig_width < min_width or orig_height < min_height:
|
||||
aspect_ratio = orig_width / orig_height
|
||||
if min_width / aspect_ratio >= min_height:
|
||||
width = min_width
|
||||
height = int(min_width / aspect_ratio)
|
||||
else:
|
||||
height = min_height
|
||||
width = int(min_height * aspect_ratio)
|
||||
|
||||
# Ensure the dimensions are at least min_width and min_height
|
||||
width = max(width, min_width)
|
||||
height = max(height, min_height)
|
||||
|
||||
elif mode == "factor":
|
||||
width = round(orig_width * rescale_factor)
|
||||
height = round(orig_height * rescale_factor)
|
||||
|
||||
# Resize
|
||||
if orig_width != width or orig_height != height:
|
||||
samples = one_image
|
||||
samples = samples.movedim(-1, 1)
|
||||
samples = rescale(samples, width, height, rescale_algorithm)
|
||||
samples = samples.movedim(1, -1)
|
||||
one_image = samples
|
||||
|
||||
samples = one_mask
|
||||
samples = samples.unsqueeze(1)
|
||||
samples = rescale(samples, width, height, "nearest")
|
||||
samples = samples.squeeze(1)
|
||||
one_mask = samples
|
||||
|
||||
if one_context_mask is not None:
|
||||
samples = one_context_mask
|
||||
samples = samples.unsqueeze(1)
|
||||
samples = rescale(samples, width, height, "nearest")
|
||||
samples = samples.squeeze(1)
|
||||
one_context_mask = samples
|
||||
|
||||
# Append results
|
||||
results_image.append(one_image.squeeze(0))
|
||||
results_mask.append(one_mask.squeeze(0))
|
||||
if one_context_mask is not None:
|
||||
results_context_mask.append(one_context_mask.squeeze(0))
|
||||
|
||||
# Stack the results to form batches
|
||||
output_image = torch.stack(results_image, dim=0)
|
||||
output_mask = torch.stack(results_mask, dim=0)
|
||||
output_context_mask = None
|
||||
if optional_context_mask is not None:
|
||||
output_context_mask = torch.stack(results_context_mask, dim=0)
|
||||
|
||||
return (output_image, output_mask, output_context_mask)
|
||||
+1
-1
@@ -1,7 +1,7 @@
|
||||
[project]
|
||||
name = "comfyui-inpaint-cropandstitch"
|
||||
description = "The '✂️ Inpaint Crop' and '✂️ Inpaint Stitch' nodes enable inpainting only on masked area very easily: crop the image around the masked area with the Crop node, then use any standard workflow for sampling, then connect the sampled image to the Stitch node, which will put it back in place in the original image. These nodes enable faster sampling of smaller areas and take care of downsampling and upsampling to fit specific model and resource needs."
|
||||
version = "2.1.9"
|
||||
version = "3.0.0"
|
||||
license = { file = "LICENSE" }
|
||||
|
||||
[project.urls]
|
||||
|
||||
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
File diff suppressed because it is too large
Load Diff

Binary file not shown.
|
After Width: | Height: | Size: 55 KiB |
Reference in New Issue
Block a user