update readme.md
 Jingfeng727

|
After Width: | Height: | Size: 247 KiB |

|
After Width: | Height: | Size: 301 KiB |

|
After Width: | Height: | Size: 230 KiB |

|
After Width: | Height: | Size: 353 KiB |

|
After Width: | Height: | Size: 32 KiB |

|
After Width: | Height: | Size: 144 KiB |

|
After Width: | Height: | Size: 126 KiB |

|
After Width: | Height: | Size: 138 KiB |

|
After Width: | Height: | Size: 170 KiB |

|
After Width: | Height: | Size: 273 KiB |

|
After Width: | Height: | Size: 119 KiB |

|
After Width: | Height: | Size: 433 KiB |

|
After Width: | Height: | Size: 155 KiB |
@@ -0,0 +1,133 @@
|
||||
<h1 align="center"> Locate, Assign, Refine: Taming Customized Image Inpainting with Text-Subject Guidance </h1>
|
||||
|
||||
<p align="center">
|
||||
<strong>Yulin Pan</strong>
|
||||
·
|
||||
<strong>Chaojie Mao</strong>
|
||||
·
|
||||
<strong>Zeyinzi Jiang</strong>
|
||||
·
|
||||
<strong>Zhen Han</strong>
|
||||
·
|
||||
<strong>Jingfeng Zhang</strong>
|
||||
<br>
|
||||
<a href="https://arxiv.org/abs/2403.19534"><img src="https://img.shields.io/static/v1?label=arXiv&message=LARGen&color=red&logo=arxiv"></a>
|
||||
<a href="https://ali-vilab.github.io/largen-page/"><img src="https://img.shields.io/badge/Page-LARGen-Gree"></a>
|
||||
</p>
|
||||
|
||||
LARGen is a unified image inpainting framework that supports text-guided, subject-guided and text-subject-guided inpainting simutaneously.
|
||||
Four LARGen-based fantastic applications are now supported by SCEPTER Studio:
|
||||
1. Zoom Out
|
||||
2. Virtual Try On
|
||||
3. Text-Guided Inpainting
|
||||
4. Text-Subject-Guided Inpainting
|
||||
|
||||
## Basic Usage
|
||||
|
||||
Here's a demo showcasing the use of LARGen-based functions.
|
||||
<p align="left">
|
||||
<img src="https://raw.githubusercontent.com/ali-vilab/largen-page/main/public/images/largen.gif" width="1300">
|
||||
</p>
|
||||
|
||||
## Gallery
|
||||
|
||||
### LAR-Gen: Zoom Out
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Origin Image</strong><br>Prompt: a temple on fire</td>
|
||||
<td><strong>Zoom-Out</strong><br>CenterAround:0.75</td>
|
||||
<td><strong>Zoom-Out</strong><br>CenterAround:0.75</td>
|
||||
<td><strong>Zoom-Out</strong><br>CenterAround:0.75</td>
|
||||
<td><strong>Zoom-Out</strong><br>CenterAround:0.75</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="../../../asset/images/zoom_out/ex1_scene_im.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/zoom_out/ex1_zoom_out1.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/zoom_out/ex1_zoom_out2.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/zoom_out/ex1_zoom_out3.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/zoom_out/ex1_zoom_out4.jpg" width="240"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### LAR-Gen: Virtual Try-on
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Model Image</strong></td>
|
||||
<td><strong>Model Mask</strong></td>
|
||||
<td><strong>Clothing Image</strong></td>
|
||||
<td><strong>Clothing Mask</strong></td>
|
||||
<td><strong>Try-on Output</strong></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="../../../asset/images/virtual_try_on/model.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/virtual_try_on/ex2_scene_mask.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/virtual_try_on/tshirt.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/virtual_try_on/ex2_subject_mask.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/virtual_try_on/try_on_out.jpg" width="240"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### LAR-Gen: Inpainting (Text guided)
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Origin Image</strong><br>Prompt: a blue and white porcelain</td>
|
||||
<td><strong>Inpainting Mask1</strong></td>
|
||||
<td><strong>Inpainting Output1</strong></td>
|
||||
<td><strong>Inpainting Mask2</strong><br>Prompt: a clock</td>
|
||||
<td><strong>Inpainting Output2</strong></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="../../../asset/images/inpainting_text/ex3_scene_im.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/inpainting_text/ex3_scene_mask.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/inpainting_text/inpainting_text.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/inpainting_text/ex3_scene_mask2.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/inpainting_text/inpainting_text2.jpg" width="240"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### LAR-Gen: Inpainting (Text and Subject guided)
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Origin Image</strong><br>Prompt: a dog wearing sunglasses</td>
|
||||
<td><strong>Origin Mask</strong></td>
|
||||
<td><strong>Reference Image</strong></td>
|
||||
<td><strong>Reference Mask</strong></td>
|
||||
<td><strong>Inpainting Output</strong></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="../../../asset/images/inpainting_text_ref/ex4_scene_im.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/inpainting_text_ref/ex4_scene_mask.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/inpainting_text_ref/ex4_subject_im.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/inpainting_text_ref/ex4_subject_mask.jpg" width="240"></td>
|
||||
<td><img src="../../../asset/images/inpainting_text_ref/inpainting_text_ref.jpg" width="240"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
## Features
|
||||
|
||||
| **Model** | **Locate** | **Assign** | **Refine** |
|
||||
|:---------:|:----------:|:----------:|:----------:|
|
||||
| SD v1.5 | ⏳ | ⏳ | ⏳ |
|
||||
| SD XL | 🪄 | 🪄 | ⏳ |
|
||||
|
||||
- 🪄 denotes that the feature has been supported.
|
||||
- ⏳ denotes that the feature has not been integrated currently.
|
||||
|
||||
|
||||
## Pretrained Models
|
||||
|
||||
| **Model** | **URL** |
|
||||
|:----------:|:-------:|
|
||||
| largen-sdxl-s22k | [ModelScope](https://www.modelscope.cn/models/iic/LARGEN/summary) |
|
||||
|
||||
|
||||
## BibTeX
|
||||
If our work is useful for your research, please consider citing:
|
||||
```bibtex
|
||||
@article{pan2024locate,
|
||||
title={Locate, Assign, Refine: Taming Customized Image Inpainting with Text-Subject Guidance},
|
||||
author={Pan, Yulin and Mao, Chaojie and Jiang, Zeyinzi and Han, Zhen and Zhang, Jingfeng},
|
||||
journal={arXiv preprint arXiv:2403.19534},
|
||||
year={2024}
|
||||
}
|
||||
```
|
||||
@@ -0,0 +1,127 @@
|
||||
<p align="center">
|
||||
|
||||
<h2 align="center">SCEdit: Efficient and Controllable Image Diffusion Generation via Skip Connection Editing</h2>
|
||||
<h3 align="center">(CVPR 2024 Highlight)</h3>
|
||||
<p align="center">
|
||||
<strong>Zeyinzi Jiang</strong>
|
||||
·
|
||||
<strong>Chaojie Mao</strong>
|
||||
·
|
||||
<strong>Yulin Pan</strong>
|
||||
·
|
||||
<strong>Zhen Han</strong>
|
||||
·
|
||||
<strong>Jingfeng Zhang</strong>
|
||||
<br>
|
||||
<b>Alibaba Group</b>
|
||||
<br>
|
||||
<a href="https://arxiv.org/abs/2312.11392"><img src='https://img.shields.io/badge/arXiv-SCEdit-red' alt='Paper PDF'></a>
|
||||
<a href='https://scedit.github.io/'><img src='https://img.shields.io/badge/Project_Page-SCEdit-green' alt='Project Page'></a>
|
||||
<a href='https://github.com/modelscope/scepter'><img src='https://img.shields.io/badge/scepter-SCEdit-yellow'></a>
|
||||
<a href='https://github.com/modelscope/swift'><img src='https://img.shields.io/badge/swift-SCEdit-blue'></a>
|
||||
<br>
|
||||
</p>
|
||||
|
||||
SCEdit is an efficient generative fine-tuning framework proposed by Alibaba TongYi Vision Intelligence Lab. This framework enhances the fine-tuning capabilities for text-to-image generation downstream tasks and enables quick adaptation to specific generative scenarios, **saving 30%-50% of training memory costs compared to LoRA**. Furthermore, it can be directly extended to controllable image generation tasks, **requiring only 7.9% of the parameters that ControlNet needs for conditional generation and saving 30% of memory usage**. It supports various conditional generation tasks including edge maps, depth maps, segmentation maps, poses, color maps, and image completion.
|
||||
|
||||
## Usage
|
||||
|
||||
### Text-to-Image Generation
|
||||
```shell
|
||||
# SD v1.5
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/t2i/sd15_512_sce_t2i.yaml
|
||||
# SD v2.1
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/t2i/sd21_768_sce_t2i.yaml
|
||||
# SD XL
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/t2i/sdxl_1024_sce_t2i.yaml
|
||||
```
|
||||
|
||||
### Controllable Image Synthesis
|
||||
```shell
|
||||
# SD v1.5 + hed
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sd15_512_sce_ctr_hed.yaml
|
||||
# SD v2.1 + canny
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sd21_768_sce_ctr_canny.yaml
|
||||
# SD XL + depth
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sdxl_1024_sce_ctr_depth.yaml
|
||||
```
|
||||
|
||||
### Gradio
|
||||
```shell
|
||||
python -m scepter.tools.webui # Then click [Use Tuners] or [Use Controller]
|
||||
```
|
||||
|
||||
## Models
|
||||
|
||||
### Model URL
|
||||
|
||||
| Model | URL |
|
||||
|--------|-------------------------------------------------------------------------------------------------------------------------------------------|
|
||||
| SCEdit | [ModelScope](https://modelscope.cn/models/iic/scepter_scedit/summary) [HuggingFace](https://huggingface.co/scepter-studio/scepter_scedit) |
|
||||
|
||||
### Text-to-Image Generation
|
||||
|
||||
| **Model** | **SCEdit** |
|
||||
|:---------:|:----------:|
|
||||
| SD 1.5 | 🪄 |
|
||||
| SD 2.1 | 🪄 |
|
||||
| SD XL | 🪄 |
|
||||
|
||||
### Controllable Image Synthesis
|
||||
|
||||
| **Model** | **Canny** | **HED** | **Depth** | **Pose** | **Color** |
|
||||
|:---------:|:---------:|:-------:|:---------:|:--------:|:---------:|
|
||||
| SD 2.1 | 🪄 | 🪄 | 🪄 | 🪄 | 🪄 |
|
||||
| SD XL | 🪄 | 🪄 | 🪄 | 🪄 | 🪄 |
|
||||
|
||||
|
||||
## Application Gallery
|
||||
|
||||
### Dragon Year Special: Dragon Tuner
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Gold Dragon Tuner</strong></td>
|
||||
<td><strong>Sloppy Dragon Tuner</strong></td>
|
||||
<td><strong>Red Dragon Tuner</strong><br> + Papercraft Mantra</td>
|
||||
<td><strong>Azure Dragon Tuner</strong><br> + Pose Control</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="../../../asset/images/scedit/tuner_gold_dragon.jpeg" width="300"></td>
|
||||
<td><img src="../../../asset/images/scedit/tuner_sloppy_dragon.jpeg" width="300"></td>
|
||||
<td><img src="../../../asset/images/scedit/tuner_mantra_papercraft_dragon.jpeg" width="300"></td>
|
||||
<td><img src="../../../asset/images/scedit/tuner_pose.jpeg" width="300"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Text Effect Image
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Conditional Image</strong></td>
|
||||
<td><strong>Midas Control</strong><br>"Race track, top view"</td>
|
||||
<td><strong>Midas Control</strong><br> + Watercolor Mantra<br>"white lilies"</td>
|
||||
<td><strong>Midas Control</strong><br> + Dragon Tuner<br>"Spring Festival, Chinese dragon"</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="../../../asset/images/scedit/word_condition.png" width="300"></td>
|
||||
<td><img src="../../../asset/images/scedit/word_race.jpeg" width="300"></td>
|
||||
<td><img src="../../../asset/images/scedit/word_lilies.jpeg" width="300"></td>
|
||||
<td><img src="../../../asset/images/scedit/word_festival.jpeg" width="300"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
|
||||
## BibTeX
|
||||
|
||||
```bibtex
|
||||
@article{jiang2023scedit,
|
||||
title = {SCEdit: Efficient and Controllable Image Diffusion Generation via Skip Connection Editing},
|
||||
author = {Jiang, Zeyinzi and Mao, Chaojie and Pan, Yulin and Han, Zhen and Zhang, Jingfeng},
|
||||
year = {2023},
|
||||
journal = {arXiv preprint arXiv:2312.11392}
|
||||
}
|
||||
```
|
||||
|
||||
|
||||
@@ -0,0 +1,103 @@
|
||||
|
||||
# StyleBooth: Image Style Editing with Multimodal Instruction
|
||||
|
||||
Zhen Han, Chaojie Mao, Zeyinzi Jiang, Yulin Pan, Jingfeng Zhang
|
||||
|
||||
Alibaba Group
|
||||
|
||||
[[paper](https://arxiv.org/abs/2404.12154)][[Model](https://modelscope.cn/models/iic/stylebooth/summary)] [[Dataset](https://modelscope.cn/models/iic/stylebooth/summary)]
|
||||
|
||||
## Abstract
|
||||
|
||||
Given an original image, image editing aims to generate an image that align with the provided instruction. The challenges are to accept multimodal inputs as instructions and a scarcity of high-quality training data, including crucial triplets of source/target image pairs and multimodal (text and image) instructions. In this paper, we focus on image style editing and present <strong>StyleBooth</strong>, a method that proposes a comprehensive framework for image editing and a feasible strategy for building a high-quality style editing dataset. We integrate encoded textual instruction and image exemplar as a unified condition for diffusion model, enabling the editing of original image following <strong>multimodal instructions</strong>. Furthermore, by <strong>iterative style-destyle tuning and editing</strong> and usability filtering, the StyleBooth dataset provides content-consistent stylized/plain image pairs in various categories of styles. To show the flexibility of StyleBooth, we conduct experiments on diverse tasks, such as textbased style editing, exemplar-based style editing and compositional style editing. The results demonstrate that the quality and variety of training data significantly enhance the ability to preserve content and improve the overall quality of generated images in editing tasks.
|
||||
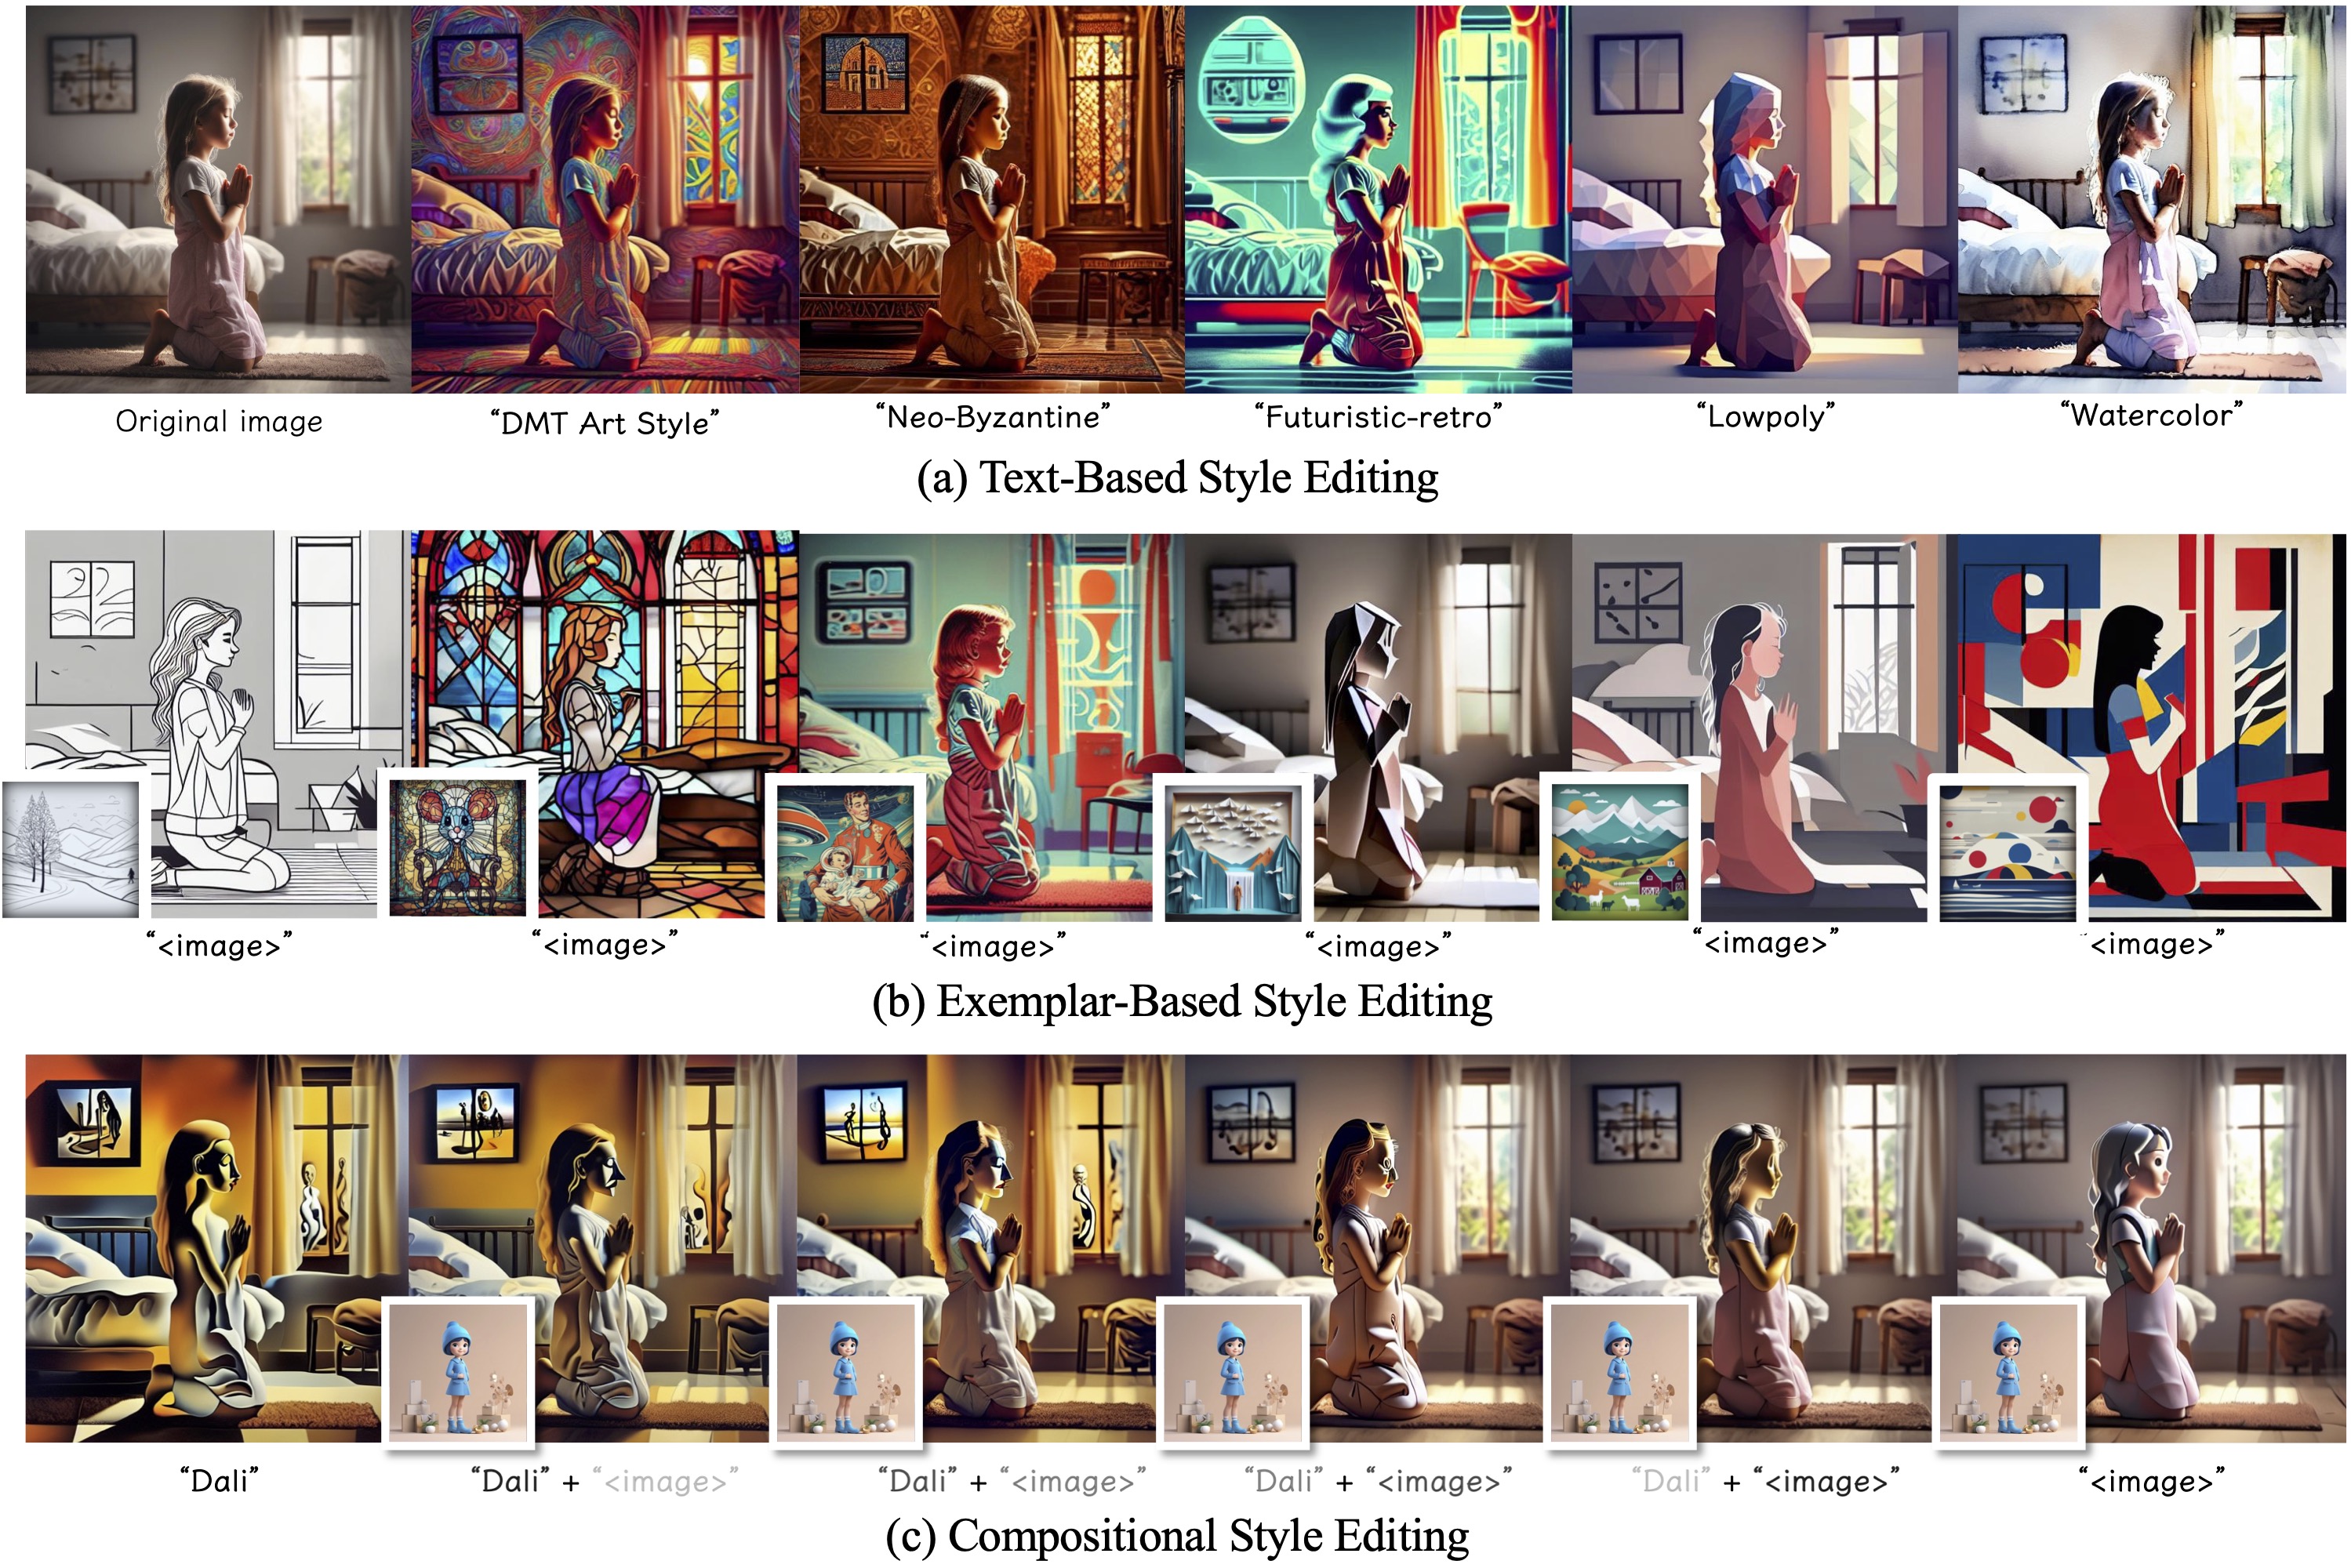
|
||||
|
||||
## Gallery
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Origin Image</strong><br>Gold Dragon Tuner</td>
|
||||
<td><strong>Graffiti Art</strong></td>
|
||||
<td><strong>Adorable Kawaii</strong></td>
|
||||
<td><strong>game-retro game</strong></td>
|
||||
<td><strong>Vincent van Gogh</strong></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="../../../asset/images/scedit/tuner_gold_dragon.jpeg" width="240"></td>
|
||||
<td><img src="../../../asset/images/stylebooth/graffiti.jpeg" width="240"></td>
|
||||
<td><img src="../../../asset/images/stylebooth/kawaii.jpeg" width="240"></td>
|
||||
<td><img src="../../../asset/images/stylebooth/retrogame.jpeg" width="240"></td>
|
||||
<td><img src="../../../asset/images/stylebooth/vangogh.jpeg" width="240"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
## Features
|
||||
|
||||
| **Text-Based** | **Exemplar-Based** |
|
||||
|:--------------:|:-----------------:|
|
||||
| 🪄 | ⏳ |
|
||||
|
||||
- ✅ indicates support for both training and inference.
|
||||
- 🪄 denotes that the model has been published.
|
||||
- ⏳ denotes that the module has not been integrated currently.
|
||||
- More models will be released in the future.
|
||||
|
||||
## Run StyleBooth
|
||||
- Code implementation: See model configuration and code based on [🪄SCEPTER](https://github.com/modelscope/scepter).
|
||||
|
||||
- Demo: Try [🖥️SCEPTER Studio](https://github.com/modelscope/scepter/tree/main?tab=readme-ov-file#%EF%B8%8F-scepter-studio).
|
||||
|
||||
- Easy run:
|
||||
Try the following example script to run StyleBooth modified from [tests/modules/test_diffusion_inference.py](https://github.com/modelscope/scepter/blob/main/tests/modules/test_diffusion_inference.py):
|
||||
|
||||
```python
|
||||
# `pip install scepter>0.0.4` or
|
||||
# clone newest SCEPTER and run `PYTHONPATH=./ python <this_script>` at the main branch root.
|
||||
import os
|
||||
import unittest
|
||||
|
||||
from PIL import Image
|
||||
from torchvision.utils import save_image
|
||||
|
||||
from scepter.modules.inference.stylebooth_inference import StyleboothInference
|
||||
from scepter.modules.utils.config import Config
|
||||
from scepter.modules.utils.file_system import FS
|
||||
from scepter.modules.utils.logger import get_logger
|
||||
|
||||
|
||||
class DiffusionInferenceTest(unittest.TestCase):
|
||||
def setUp(self):
|
||||
print(('Testing %s.%s' % (type(self).__name__, self._testMethodName)))
|
||||
self.logger = get_logger(name='scepter')
|
||||
config_file = 'scepter/methods/studio/scepter_ui.yaml'
|
||||
cfg = Config(cfg_file=config_file)
|
||||
if 'FILE_SYSTEM' in cfg:
|
||||
for fs_info in cfg['FILE_SYSTEM']:
|
||||
FS.init_fs_client(fs_info)
|
||||
self.tmp_dir = './cache/save_data/diffusion_inference'
|
||||
if not os.path.exists(self.tmp_dir):
|
||||
os.makedirs(self.tmp_dir)
|
||||
|
||||
def tearDown(self):
|
||||
super().tearDown()
|
||||
|
||||
# uncomment this line to skip this module.
|
||||
# @unittest.skip('')
|
||||
def test_stylebooth(self):
|
||||
config_file = 'scepter/methods/studio/inference/edit/stylebooth_tb_pro.yaml'
|
||||
cfg = Config(cfg_file=config_file)
|
||||
diff_infer = StyleboothInference(logger=self.logger)
|
||||
diff_infer.init_from_cfg(cfg)
|
||||
|
||||
output = diff_infer({'prompt': 'Let this image be in the style of sai-lowpoly'},
|
||||
style_edit_image=Image.open('asset/images/inpainting_text_ref/ex4_scene_im.jpg'),
|
||||
style_guide_scale_text=7.5,
|
||||
style_guide_scale_image=0.5)
|
||||
save_path = os.path.join(self.tmp_dir,
|
||||
'stylebooth_test_lowpoly_cute_dog.png')
|
||||
save_image(output['images'], save_path)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
unittest.main()
|
||||
```
|
||||
@@ -0,0 +1,26 @@
|
||||
<h1 align="center">Dataset Management</h1>
|
||||
|
||||
SCEPTER supports three types of dataset formats: TXT, CSV, and ModelScope.
|
||||
Below are examples for each format, illustrating their details and basic usage.
|
||||
|
||||
## Modelscope Format
|
||||
|
||||
We use a [custom-stylized dataset](https://modelscope.cn/datasets/damo/style_custom_dataset/summary), which included classes 3D, anime, flat illustration, oil painting, sketch, and watercolor, each with 30 image-text pairs.
|
||||
|
||||
```python
|
||||
# pip install modelscope
|
||||
from modelscope.msdatasets import MsDataset
|
||||
ms_train_dataset = MsDataset.load('style_custom_dataset', namespace='damo', subset_name='3D', split='train_short')
|
||||
print(next(iter(ms_train_dataset)))
|
||||
```
|
||||
|
||||
## CSV Format
|
||||
|
||||
For the data format used by SCEPTER Studio, please refer to [3D_example_csv.zip](https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=datasets/3D_example_csv.zip).
|
||||
|
||||
## TXT Format
|
||||
|
||||
To facilitate starting training in command-line mode, you can use a dataset in text format, please refer to [3D_example_txt.zip](https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=datasets/3D_example_txt.zip)
|
||||
|
||||
```shell
|
||||
mkdir -p cache/datasets/ && wget 'https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=datasets/3D_example_txt.zip' -O cache/datasets/3D_example_txt.zip && unzip cache/datasets/3D_example_txt.zip -d cache/datasets/ && rm cache/datasets/3D_example_txt.zip
|
||||
@@ -0,0 +1,46 @@
|
||||
# Inference
|
||||
|
||||
In this tutorial, we'll cover the use of the scepter framework for convenient inference, including inference using the command line or specific method classes, and we'll give examples of inference methods for additional tasks.
|
||||
|
||||
## Command Line
|
||||
Inference of SDXL generation models using the command line.
|
||||
```shell
|
||||
python scepter/tools/run_inference.py --cfg scepter/methods/examples/generation/stable_diffusion_xl_1024.yaml --prompt 'a cute dog' --save_folder 'inference' # generation on SD XL
|
||||
```
|
||||
|
||||
## Class Instantiation
|
||||
Inference of SD2.1 generation models using the class instantiation.
|
||||
```python
|
||||
from torchvision.utils import save_image
|
||||
from scepter.modules.utils.config import Config
|
||||
from scepter.modules.utils.file_system import FS
|
||||
from scepter.modules.utils.logger import get_logger
|
||||
from scepter.modules.inference.diffusion_inference import DiffusionInference
|
||||
# init file system - modelscope
|
||||
FS.init_fs_client(Config(load=False, cfg_dict={'NAME': 'ModelscopeFs', 'TEMP_DIR': 'cache/data'}))
|
||||
# init model config
|
||||
logger = get_logger(name='scepter')
|
||||
cfg = Config(cfg_file='scepter/methods/studio/inference/stable_diffusion/sd21_pro.yaml')
|
||||
diff_infer = DiffusionInference(logger)
|
||||
diff_infer.init_from_cfg(cfg)
|
||||
# start inference
|
||||
output = diff_infer({'prompt': 'a cute dog'})
|
||||
save_image(output['images'], 'sd21_test_prompt_a_cute_dog.png')
|
||||
```
|
||||
|
||||
## Additional Tasks
|
||||
|
||||
### Fine-tuned Model Inference
|
||||
|
||||
```shell
|
||||
python scepter/tools/run_inference.py --cfg scepter/methods/scedit/t2i/sd15_512_sce_t2i_swift.yaml --pretrained_model 'cache/save_data/sd15_512_sce_t2i_swift/checkpoints/ldm_step-100.pth' --prompt 'A close up of a small rabbit wearing a hat and scarf' --save_folder 'trained_test_prompt_rabbit'
|
||||
```
|
||||
|
||||
### Controllable Image Synthesis Inference
|
||||
|
||||
- SCEdit
|
||||
```shell
|
||||
python scepter/tools/run_inference.py --cfg scepter/methods/scedit/ctr/sd21_768_sce_ctr_canny.yaml --num_samples 1 --prompt 'a single flower is shown in front of a tree' --save_folder 'test_flower_canny' --image_size 768 --task control --image 'asset/images/flower.jpg' --control_mode canny --pretrained_model ms://damo/scepter_scedit@controllable_model/SD2.1/canny_control/0_SwiftSCETuning/pytorch_model.bin # canny
|
||||
python scepter/tools/run_inference.py --cfg scepter/methods/scedit/ctr/sd21_768_sce_ctr_pose.yaml --num_samples 1 --prompt 'super mario' --save_folder 'test_mario_pose' --image_size 768 --task control --image 'asset/images/pose_source.png' --control_mode source --pretrained_model ms://damo/scepter_scedit@controllable_model/SD2.1/pose_control/0_SwiftSCETuning/pytorch_model.bin # pose
|
||||
```
|
||||
|
||||
@@ -0,0 +1,84 @@
|
||||
# Training
|
||||
|
||||
We provide a framework for training and validation.
|
||||
|
||||
The scripts below are just for illustration purposes. To achieve better results, you can modify the corresponding parameters as needed.
|
||||
|
||||
## Start Training
|
||||
There are different ways to start a training:
|
||||
|
||||
- calling scepter/tools/run_train.py:
|
||||
```bash
|
||||
# calling at SCEPTER root:
|
||||
PYTHONPATH=./ python scepter/tools/run_train.py --cfg [path-to-your-yaml]
|
||||
|
||||
# calling scepter library:
|
||||
pip install scepter
|
||||
python -m scepter.tools.run_train --cfg [path-to-your-yaml]
|
||||
```
|
||||
- calling your own script:
|
||||
```bash
|
||||
# calling at SCEPTER root:
|
||||
PYTHONPATH=./ python [path-to-your-script] --cfg [path-to-your-yaml]
|
||||
|
||||
# calling scepter library:
|
||||
pip install scepter
|
||||
python [path-to-your-script] --cfg [path-to-your-yaml]
|
||||
```
|
||||
your scepter should be like:
|
||||
```python
|
||||
from scepter.tools.run_train import run
|
||||
|
||||
if __name__ == '__main__':
|
||||
run()
|
||||
```
|
||||
|
||||
## Popular Tasks
|
||||
### Text-to-Image Generation
|
||||
|
||||
- SCEdit
|
||||
```bash
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/t2i/sd15_512_sce_t2i.yaml # SD v1.5
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/t2i/sd21_768_sce_t2i.yaml # SD v2.1
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/t2i/sdxl_1024_sce_t2i.yaml # SD XL
|
||||
```
|
||||
|
||||
- Existing Tuning Strategies
|
||||
```bash
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/examples/generation/stable_diffusion_1.5_512.yaml # fully-tuning on SD v1.5
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/examples/generation/stable_diffusion_2.1_768_lora.yaml # lora-tuning on SD v2.1
|
||||
```
|
||||
|
||||
- Data Text Format
|
||||
```bash
|
||||
# Download the 3D_example_txt.zip as previously mentioned
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/t2i/sdxl_1024_sce_t2i_datatxt.yaml
|
||||
```
|
||||
|
||||
### Controllable Image Synthesis
|
||||
|
||||
- SCEdit
|
||||
|
||||
The YAML configuration can be modified to combine different base models and conditions. The following is provided as an example.
|
||||
```bash
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sd15_512_sce_ctr_hed.yaml # SD v1.5 + hed
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sd21_768_sce_ctr_canny.yaml # SD v2.1 + canny
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sd21_768_sce_ctr_pose.yaml # SD v2.1 + pose
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sdxl_1024_sce_ctr_depth.yaml # SD XL + depth
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sdxl_1024_sce_ctr_color.yaml # SD XL + color
|
||||
```
|
||||
|
||||
- Data Text Format
|
||||
```bash
|
||||
# Download the 3D_example_txt.zip as previously mentioned
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sdxl_1024_sce_ctr_color_datatxt.yaml
|
||||
```
|
||||
|
||||
|
||||
## Customize Modules
|
||||
You can register your own Modules like DATASET, SAMPLERS, TRANSFORMS, MODELS, SOVLERS, HOOKS, OPTIMIZERS into SCEPTER.
|
||||
Refer to `example/`, build the modules of your task in `example/{task}`.
|
||||
```bash
|
||||
cd example/classifier
|
||||
python run.py --cfg classifier.yaml
|
||||
```
|
||||
@@ -8,20 +8,17 @@
|
||||
<a href="https://github.com/modelscope/scepter/"><img src="https://img.shields.io/badge/scepter-Build from source-6FEBB9.svg"></a>
|
||||
</p>
|
||||
|
||||
## 📖 Table of Contents
|
||||
- [News](#-news)
|
||||
- [Introduction](#-introduction)
|
||||
- [Installation](#%EF%B8%8F-installation)
|
||||
- [Getting Started](#-getting-started)
|
||||
- [SCEPTER Studio](#%EF%B8%8F-scepter-studio)
|
||||
- [Gallery](#%EF%B8%8F-gallery)
|
||||
- [Features](#-features)
|
||||
- [Learn More](#-learn-more)
|
||||
- [License](#license)
|
||||
- [Acknowledgement](#acknowledgement)
|
||||
🪄SCEPTER is an open-source code repository dedicated to generative training, fine-tuning, and inference, encompassing a suite of downstream tasks such as image generation, transfer, editing.
|
||||
SCEPTER integrates popular community-driven implementations as well as proprietary methods by Tongyi Lab of Alibaba Group, offering a comprehensive toolkit for researchers and practitioners in the field of AIGC. This versatile library is designed to facilitate innovation and accelerate development in the rapidly evolving domain of generative models.
|
||||
|
||||
SCEPTER offers 3 core components:
|
||||
- [Generative training and inference framework](#tutorials)
|
||||
- [Easy implementation of popular approaches](#currently-supported-approaches)
|
||||
- [Interactive user interface: SCEPTER Studio](#launch)
|
||||
|
||||
|
||||
## 🎉 News
|
||||
- [2024.04]: New [StyleBooth](https://ali-vilab.github.io/stylebooth-page/) demo on SCEPTER Studio, supporting `Text-Based Style Editing`.
|
||||
- [2024.04]: New [StyleBooth](https://ali-vilab.github.io/stylebooth-page/) demo on SCEPTER Studio for`Text-Based Style Editing`.
|
||||
- [2024.03]: We optimize the training UI and checkpoint management. New [LAR-Gen](https://arxiv.org/abs/2403.19534) model has been added on SCEPTER Studio, supporting `zoom-out`, `virtual try on`, `inpainting`.
|
||||
- [2024.02]: We release new SCEdit controllable image synthesis models for SD v2.1 and SD XL. Multiple strategies applied to accelerate inference time for SCEPTER Studio.
|
||||
- [2024.01]: We release **SCEPTER Studio**, an integrated toolkit for data management, model training and inference based on [Gradio](https://www.gradio.app/).
|
||||
@@ -29,30 +26,44 @@
|
||||
- [2023.12]: We propose [SCEdit](https://arxiv.org/abs/2312.11392), an efficient and controllable generation framework.
|
||||
- [2023.12]: We release [🪄SCEPTER](https://github.com/modelscope/scepter/) library.
|
||||
|
||||
## 📝 Introduction
|
||||
|
||||
SCEPTER is an open-source code repository dedicated to generative training, fine-tuning, and inference, encompassing a suite of downstream tasks such as image generation, transfer, editing. It integrates popular community-driven implementations as well as proprietary methods by Tongyi Lab of Alibaba Group, offering a comprehensive toolkit for researchers and practitioners in the field of AIGC. This versatile library is designed to facilitate innovation and accelerate development in the rapidly evolving domain of generative models.
|
||||
## 🖼 Gallery for Recent Works
|
||||
|
||||
Main Feature:
|
||||
### StyleBooth
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Origin Image</strong><br>Gold Dragon Tuner</td>
|
||||
<td><strong>Graffiti Art</strong></td>
|
||||
<td><strong>Adorable Kawaii</strong></td>
|
||||
<td><strong>game-retro game</strong></td>
|
||||
<td><strong>Vincent van Gogh</strong></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="asset/images/scedit/tuner_gold_dragon.jpeg" width="240"></td>
|
||||
<td><img src="asset/images/stylebooth/graffiti.jpeg" width="240"></td>
|
||||
<td><img src="asset/images/stylebooth/kawaii.jpeg" width="240"></td>
|
||||
<td><img src="asset/images/stylebooth/retrogame.jpeg" width="240"></td>
|
||||
<td><img src="asset/images/stylebooth/vangogh.jpeg" width="240"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
- Task:
|
||||
- Text-to-image generation
|
||||
- Controllable image synthesis
|
||||
- Image editing
|
||||
- Training / Inference:
|
||||
- Distribute: DDP / FSDP / FairScale / Xformers
|
||||
- File system: Local / Http / OSS / Modelscope
|
||||
- Deploy:
|
||||
- Data management
|
||||
- Training
|
||||
- Inference
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Origin Image</strong></td>
|
||||
<td><strong>Lowpoly</strong></td>
|
||||
<td><strong>Colored Pencil Art</strong></td>
|
||||
<td><strong>Watercolor</strong></td>
|
||||
<td><strong>misc-disco</strong></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="asset/images/stylebooth/mountain.jpg" width="240"></td>
|
||||
<td><img src="asset/images/stylebooth/lowpoly.jpg" width="240"></td>
|
||||
<td><img src="asset/images/stylebooth/colorpencil.jpeg" width="240"></td>
|
||||
<td><img src="asset/images/stylebooth/watercolor.jpeg" width="240"></td>
|
||||
<td><img src="asset/images/stylebooth/disco.jpeg" width="240"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
Currently supported approaches (and counting):
|
||||
|
||||
1. SD Series: [Stable Diffusion v1.5](https://huggingface.co/runwayml/stable-diffusion-v1-5) / [Stable Diffusion v2.1](https://huggingface.co/runwayml/stable-diffusion-v1-5) / [Stable Diffusion XL](https://huggingface.co/stabilityai/stable-diffusion-xl-base-1.0)
|
||||
2. SCEdit(CVPR2024): [SCEdit: Efficient and Controllable Image Diffusion Generation via Skip Connection Editing](https://arxiv.org/abs/2312.11392) [](https://arxiv.org/abs/2312.11392) [](https://scedit.github.io/)
|
||||
3. Res-Tuning(NeurIPS2023 TODO): [Res-Tuning: A Flexible and Efficient Tuning Paradigm via Unbinding Tuner from Backbone](https://arxiv.org/abs/2310.19859) [](https://arxiv.org/abs/2310.19859) [](https://res-tuning.github.io/)
|
||||
4. LAR-Gen: [Locate, Assign, Refine: Taming Customized Image Inpainting with Text-Subject Guidance](https://arxiv.org/abs/2403.19534) [](https://arxiv.org/abs/2403.19534) [](https://ali-vilab.github.io/largen-page/)
|
||||
|
||||
## 🛠️ Installation
|
||||
|
||||
@@ -74,107 +85,31 @@ pip install -r requirements/recommended.txt
|
||||
pip install scepter
|
||||
```
|
||||
|
||||
## 🚀 Getting Started
|
||||
## 🧩 Generative Framework
|
||||
|
||||
### Dataset
|
||||
### Tutorials
|
||||
|
||||
#### Modelscope Format
|
||||
| Documentation | Key Features |
|
||||
|:---------------------------------------------------|:----------------------------------|
|
||||
| [Train](docs/en/tutorials/train.md) | DDP / FSDP / FairScale / Xformers |
|
||||
| [Inference](docs/en/tutorials/inference.md) | Dynamic load/unload |
|
||||
| [Dataset Management](docs/en/tutorials/dataset.md) | Local / Http / OSS / Modelscope |
|
||||
|
||||
We use a [custom-stylized dataset](https://modelscope.cn/datasets/damo/style_custom_dataset/summary), which included classes 3D, anime, flat illustration, oil painting, sketch, and watercolor, each with 30 image-text pairs.
|
||||
|
||||
```python
|
||||
# pip install modelscope
|
||||
from modelscope.msdatasets import MsDataset
|
||||
ms_train_dataset = MsDataset.load('style_custom_dataset', namespace='damo', subset_name='3D', split='train_short')
|
||||
print(next(iter(ms_train_dataset)))
|
||||
```
|
||||
## 📝 Popular Approaches
|
||||
|
||||
#### CSV Format
|
||||
### Currently supported approaches
|
||||
|
||||
For the data format used by SCEPTER Studio, please refer to [3D_example_csv.zip](https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=datasets/3D_example_csv.zip).
|
||||
|
||||
#### TXT Format
|
||||
|
||||
To facilitate starting training in command-line mode, you can use a dataset in text format, please refer to [3D_example_txt.zip](https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=datasets/3D_example_txt.zip)
|
||||
|
||||
```shell
|
||||
mkdir -p cache/datasets/ && wget 'https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=datasets/3D_example_txt.zip' -O cache/datasets/3D_example_txt.zip && unzip cache/datasets/3D_example_txt.zip -d cache/datasets/ && rm cache/datasets/3D_example_txt.zip
|
||||
```
|
||||
|
||||
### Training
|
||||
|
||||
We provide a framework for training and inference, so the script below is just for illustration purposes. To achieve better results, you can modify the corresponding parameters as needed.
|
||||
|
||||
#### Text-to-Image Generation
|
||||
|
||||
- SCEdit
|
||||
```python
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/t2i/sd15_512_sce_t2i.yaml # SD v1.5
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/t2i/sd21_768_sce_t2i.yaml # SD v2.1
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/t2i/sdxl_1024_sce_t2i.yaml # SD XL
|
||||
```
|
||||
|
||||
- Existing Tuning Strategies
|
||||
```python
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/examples/generation/stable_diffusion_1.5_512.yaml # fully-tuning on SD v1.5
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/examples/generation/stable_diffusion_2.1_768_lora.yaml # lora-tuning on SD v2.1
|
||||
```
|
||||
|
||||
- Data Text Format
|
||||
```python
|
||||
# Download the 3D_example_txt.zip as previously mentioned
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/t2i/sdxl_1024_sce_t2i_datatxt.yaml
|
||||
```
|
||||
|
||||
#### Controllable Image Synthesis
|
||||
|
||||
- SCEdit
|
||||
|
||||
The YAML configuration can be modified to combine different base models and conditions. The following is provided as an example.
|
||||
```python
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sd15_512_sce_ctr_hed.yaml # SD v1.5 + hed
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sd21_768_sce_ctr_canny.yaml # SD v2.1 + canny
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sd21_768_sce_ctr_pose.yaml # SD v2.1 + pose
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sdxl_1024_sce_ctr_depth.yaml # SD XL + depth
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sdxl_1024_sce_ctr_color.yaml # SD XL + color
|
||||
```
|
||||
|
||||
- Data Text Format
|
||||
```python
|
||||
# Download the 3D_example_txt.zip as previously mentioned
|
||||
python scepter/tools/run_train.py --cfg scepter/methods/scedit/ctr/sdxl_1024_sce_ctr_color_datatxt.yaml
|
||||
```
|
||||
|
||||
### Inference
|
||||
|
||||
#### Base Model Inference
|
||||
|
||||
```python
|
||||
python scepter/tools/run_inference.py --cfg scepter/methods/examples/generation/stable_diffusion_1.5_512.yaml --prompt 'a cute dog' --save_folder 'inference' # generation on SD v1.5
|
||||
python scepter/tools/run_inference.py --cfg scepter/methods/examples/generation/stable_diffusion_2.1_768.yaml --prompt 'a cute dog' --save_folder 'inference' # generation on SD v2.1
|
||||
python scepter/tools/run_inference.py --cfg scepter/methods/examples/generation/stable_diffusion_xl_1024.yaml --prompt 'a cute dog' --save_folder 'inference' # generation on SD XL
|
||||
```
|
||||
|
||||
#### Fine-tuned Model Inference
|
||||
|
||||
```python
|
||||
python scepter/tools/run_inference.py --cfg scepter/methods/scedit/t2i/sd15_512_sce_t2i_swift.yaml --pretrained_model 'cache/save_data/sd15_512_sce_t2i_swift/checkpoints/ldm_step-100.pth' --prompt 'A close up of a small rabbit wearing a hat and scarf' --save_folder 'trained_test_prompt_rabbit'
|
||||
```
|
||||
|
||||
#### Controllable Image Synthesis Inference
|
||||
|
||||
- SCEdit
|
||||
```python
|
||||
python scepter/tools/run_inference.py --cfg scepter/methods/scedit/ctr/sd21_768_sce_ctr_canny.yaml --num_samples 1 --prompt 'a single flower is shown in front of a tree' --save_folder 'test_flower_canny' --image_size 768 --task control --image 'asset/images/flower.jpg' --control_mode canny --pretrained_model ms://damo/scepter_scedit@controllable_model/SD2.1/canny_control/0_SwiftSCETuning/pytorch_model.bin # canny
|
||||
python scepter/tools/run_inference.py --cfg scepter/methods/scedit/ctr/sd21_768_sce_ctr_pose.yaml --num_samples 1 --prompt 'super mario' --save_folder 'test_mario_pose' --image_size 768 --task control --image 'asset/images/pose_source.png' --control_mode source --pretrained_model ms://damo/scepter_scedit@controllable_model/SD2.1/pose_control/0_SwiftSCETuning/pytorch_model.bin # pose
|
||||
```
|
||||
|
||||
### Customize Modules
|
||||
Refer to `example`, build the modules of your task in `example/{task}`.
|
||||
```python
|
||||
cd example/classifier
|
||||
python run.py --cfg classifier.yaml
|
||||
```
|
||||
| Tasks | Methods | Links |
|
||||
|:----------------------------:|:--------------------------------------------:|:------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
|
||||
| Text-to-image generation | SD v1.5 | [](https://huggingface.co/runwayml/stable-diffusion-v1-5) |
|
||||
| Text-to-image generation | SD v2.1 | [](https://huggingface.co/runwayml/stable-diffusion-v1-5) |
|
||||
| Text-to-image generation | SD-XL | [](https://huggingface.co/stabilityai/stable-diffusion-xl-base-1.0) |
|
||||
| Efficent Tuning | LoRA | [](https://arxiv.org/abs/2106.09685) |
|
||||
| Efficent Tuning | Res-Tuning(NeurIPS23) | [](https://arxiv.org/abs/2310.19859) [](https://res-tuning.github.io/) |
|
||||
| Controllable image synthesis | [🌟SCEdit(CVPR24)](docs/en/tasks/scedit.md) | [](https://arxiv.org/abs/2312.11392) [](https://scedit.github.io/) |
|
||||
| Image editing | [🌟LAR-Gen](docs/en/tasks/largen.md) | [](https://arxiv.org/abs/2403.19534) [](https://ali-vilab.github.io/largen-page/) |
|
||||
| Image editing | [🌟StyleBooth](docs/en/tasks/stylebooth.md) | [](https://arxiv.org/abs/2404.12154) [](https://ali-vilab.github.io/stylebooth-page/) |
|
||||
|
||||
|
||||
## 🖥️ SCEPTER Studio
|
||||
@@ -197,189 +132,15 @@ The startup of **SCEPTER Studio** eliminates the need for manual downloading and
|
||||
Depending on the network and hardware situation, the initial startup usually requires 15-60 minutes, primarily involving the download and processing of SDv1.5, SDv2.1, and SDXL models.
|
||||
Therefore, subsequent startups will become much faster (about one minute) as downloading is no longer required.
|
||||
|
||||
* LAR-Gen: we release `zoom-out`, `virtual try on`, `inpainting(text guided)`, `inpainting(text + reference image guided)` image editing capabilities.
|
||||
Please note that the **Data Preprocess** button must be clicked before clicking the **Generate** button.
|
||||
<p align="center">
|
||||
<img src="https://raw.githubusercontent.com/ali-vilab/largen-page/main/public/images/largen.gif">
|
||||
</p>
|
||||
### Usage Demo
|
||||
|
||||
### Modelscope Studio
|
||||
| [Image Editing](https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=assets%2Fscepter_studio%2Fimage_editing_20240419.webm) | [Training](https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=assets%2Fscepter_studio%2Ftraining_20240419.webm) | [Model Sharing](https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=assets%2Fscepter_studio%2Fmodel_sharing_20240419.webm) | [Model Inference](https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=assets%2Fscepter_studio%2Fmodel_inference_20240419.webm) | [Data Management](https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=assets%2Fscepter_studio%2Fdata_management_20240419.webm) |
|
||||
|:----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------:|:-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------:|:-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------:|:-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------:|:--------------------------------------------:|
|
||||
| <video src="https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=assets%2Fscepter_studio%2Fimage_editing_20240419.webm" width="240" controls></video> | <video src="https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=assets%2Fscepter_studio%2Ftraining_20240419.webm" width="240" controls></video> | <video src="https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=assets%2Fscepter_studio%2Fmodel_sharing_20240419.webm" width="240" controls></video> | <video src="https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=assets%2Fscepter_studio%2Fmodel_inference_20240419.webm" width="240" controls></video> | <video src="https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=assets%2Fscepter_studio%2Fdata_management_20240419.webm" width="240" controls></video> |
|
||||
|
||||
We deploy a work studio on Modelscope that includes only the inference tab, please refer to [ms_scepter_studio](https://www.modelscope.cn/studios/damo/scepter_studio/summary)
|
||||
### Modelscope Studio & Huggingface Space
|
||||
|
||||
## 🖼️ Gallery
|
||||
|
||||
### StyleBooth
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Origin Image</strong><br>Gold Dragon Tuner</td>
|
||||
<td><strong>Graffiti Art</strong></td>
|
||||
<td><strong>Adorable Kawaii</strong></td>
|
||||
<td><strong>game-retro game</strong></td>
|
||||
<td><strong>Vincent van Gogh</strong></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="https://github.com/hanzhn/datas/blob/main/scepter/readme/tuner_gold_dragon.jpeg?raw=true" width="240"></td>
|
||||
<td><img src="asset/images/stylebooth/graffiti.jpeg" width="240"></td>
|
||||
<td><img src="asset/images/stylebooth/kawaii.jpeg" width="240"></td>
|
||||
<td><img src="asset/images/stylebooth/retrogame.jpeg" width="240"></td>
|
||||
<td><img src="asset/images/stylebooth/vangogh.jpeg" width="240"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
### LAR-Gen: Zoom Out
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Origin Image</strong><br>Prompt: a temple on fire</td>
|
||||
<td><strong>Zoom-Out</strong><br>CenterAround:0.75</td>
|
||||
<td><strong>Zoom-Out</strong><br>CenterAround:0.75</td>
|
||||
<td><strong>Zoom-Out</strong><br>CenterAround:0.75</td>
|
||||
<td><strong>Zoom-Out</strong><br>CenterAround:0.75</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="asset/images/zoom_out/ex1_scene_im.jpg" width="240"></td>
|
||||
<td><img src="asset/images/zoom_out/ex1_zoom_out1.jpg" width="240"></td>
|
||||
<td><img src="./asset/images/zoom_out/ex1_zoom_out2.jpg" width="240"></td>
|
||||
<td><img src="./asset/images/zoom_out/ex1_zoom_out3.jpg" width="240"></td>
|
||||
<td><img src="./asset/images/zoom_out/ex1_zoom_out4.jpg" width="240"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### LAR-Gen: Virtual Try-on
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Model Image</strong></td>
|
||||
<td><strong>Model Mask</strong></td>
|
||||
<td><strong>Clothing Image</strong></td>
|
||||
<td><strong>Clothing Mask</strong></td>
|
||||
<td><strong>Try-on Output</strong></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="asset/images/virtual_try_on/model.jpg" width="240"></td>
|
||||
<td><img src="asset/images/virtual_try_on/ex2_scene_mask.jpg" width="240"></td>
|
||||
<td><img src="asset/images/virtual_try_on/tshirt.jpg" width="240"></td>
|
||||
<td><img src="asset/images/virtual_try_on/ex2_subject_mask.jpg" width="240"></td>
|
||||
<td><img src="asset/images/virtual_try_on/try_on_out.jpg" width="240"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### LAR-Gen: Inpainting (Text guided)
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Origin Image</strong><br>Prompt: a blue and white porcelain</td>
|
||||
<td><strong>Inpainting Mask1</strong></td>
|
||||
<td><strong>Inpainting Output1</strong></td>
|
||||
<td><strong>Inpainting Mask2</strong><br>Prompt: a clock</td>
|
||||
<td><strong>Inpainting Output2</strong></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="asset/images/inpainting_text/ex3_scene_im.jpg" width="240"></td>
|
||||
<td><img src="asset/images/inpainting_text/ex3_scene_mask.jpg" width="240"></td>
|
||||
<td><img src="asset/images/inpainting_text/inpainting_text.jpg" width="240"></td>
|
||||
<td><img src="asset/images/inpainting_text/ex3_scene_mask2.jpg" width="240"></td>
|
||||
<td><img src="asset/images/inpainting_text/inpainting_text2.jpg" width="240"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### LAR-Gen: Inpainting (Text and Subject guided)
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Origin Image</strong><br>Prompt: a dog wearing sunglasses</td>
|
||||
<td><strong>Origin Mask</strong></td>
|
||||
<td><strong>Reference Image</strong></td>
|
||||
<td><strong>Reference Mask</strong></td>
|
||||
<td><strong>Inpainting Output</strong></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="asset/images/inpainting_text_ref/ex4_scene_im.jpg" width="240"></td>
|
||||
<td><img src="asset/images/inpainting_text_ref/ex4_scene_mask.jpg" width="240"></td>
|
||||
<td><img src="asset/images/inpainting_text_ref/ex4_subject_im.jpg" width="240"></td>
|
||||
<td><img src="asset/images/inpainting_text_ref/ex4_subject_mask.jpg" width="240"></td>
|
||||
<td><img src="asset/images/inpainting_text_ref/inpainting_text_ref.jpg" width="240"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Dragon Year Special: Dragon Tuner
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Gold Dragon Tuner</strong></td>
|
||||
<td><strong>Sloppy Dragon Tuner</strong></td>
|
||||
<td><strong>Red Dragon Tuner</strong><br> + Papercraft Mantra</td>
|
||||
<td><strong>Azure Dragon Tuner</strong><br> + Pose Control</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="https://github.com/hanzhn/datas/blob/main/scepter/readme/tuner_gold_dragon.jpeg?raw=true" width="300"></td>
|
||||
<td><img src="https://github.com/hanzhn/datas/blob/main/scepter/readme/tuner_sloppy_dragon.jpeg?raw=true" width="300"></td>
|
||||
<td><img src="https://github.com/hanzhn/datas/blob/main/scepter/readme/tuner_mantra_papercraft_dragon.jpeg?raw=true" width="300"></td>
|
||||
<td><img src="https://github.com/hanzhn/datas/blob/main/scepter/readme/tuner_pose.jpeg?raw=true" width="300"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Text Effect Image
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td><strong>Conditional Image</strong></td>
|
||||
<td><strong>Midas Control</strong><br>"Race track, top view"</td>
|
||||
<td><strong>Midas Control</strong><br> + Watercolor Mantra<br>"white lilies"</td>
|
||||
<td><strong>Midas Control</strong><br> + Dragon Tuner<br>"Spring Festival, Chinese dragon"</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td><img src="https://github.com/hanzhn/datas/blob/main/scepter/readme/word_condition.png?raw=true" width="300"></td>
|
||||
<td><img src="https://github.com/hanzhn/datas/blob/main/scepter/readme/word_race.jpeg?raw=true" width="300"></td>
|
||||
<td><img src="https://github.com/hanzhn/datas/blob/main/scepter/readme/word_lilies.jpeg?raw=true" width="300"></td>
|
||||
<td><img src="https://github.com/hanzhn/datas/blob/main/scepter/readme/word_festival.jpeg?raw=true" width="300"></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
## ✨ Features
|
||||
|
||||
### Text-to-Image Generation
|
||||
|
||||
| **Model** | **SCEdit** | **Full** | **LoRA** |
|
||||
|:---------:|:----------:|:--------:|:--------:|
|
||||
| SD 1.5 | 🪄 | ✅ | ✅ |
|
||||
| SD 2.1 | 🪄 | ✅ | ✅ |
|
||||
| SD XL | 🪄 | ✅ | ✅ |
|
||||
|
||||
### Controllable Image Synthesis
|
||||
- SCEdit
|
||||
|
||||
| **Model** | **Canny** | **HED** | **Depth** | **Pose** | **Color** |
|
||||
|:---------:|:---------:|:-------:|:---------:|:--------:|:---------:|
|
||||
| SD 1.5 | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| SD 2.1 | 🪄 | 🪄 | 🪄 | 🪄 | 🪄 |
|
||||
| SD XL | 🪄 | 🪄 | 🪄 | 🪄 | 🪄 |
|
||||
|
||||
### Image Editing
|
||||
- LAR-Gen
|
||||
|
||||
| **Model** | **Locate** | **Assign** | **Refine** |
|
||||
|:---------:|:----------:|:----------:|:----------:|
|
||||
| SD XL | 🪄 | 🪄 | ⏳ |
|
||||
|
||||
- StyleBooth
|
||||
|
||||
| **Text-Based** | **Exemplar-Based** |
|
||||
|:--------------:|:-----------------:|
|
||||
| 🪄 | ⏳ |
|
||||
|
||||
### Model URL
|
||||
|
||||
- ✅ indicates support for both training and inference.
|
||||
- 🪄 denotes that the model has been published.
|
||||
- ⏳ denotes that the module has not been integrated currently.
|
||||
- More models will be released in the future.
|
||||
|
||||
| Model | URL |
|
||||
|--------|-------------------------------------------------------------------------------------------------------------------------------------------|
|
||||
| SCEdit | [ModelScope](https://modelscope.cn/models/iic/scepter_scedit/summary) [HuggingFace](https://huggingface.co/scepter-studio/scepter_scedit) |
|
||||
| LAR-Gen | [ModelScope](https://www.modelscope.cn/models/iic/LARGEN/summary) |
|
||||
| StyleBooth | [ModelScope](https://www.modelscope.cn/models/iic/stylebooth/summary) |
|
||||
|
||||
PS: Scripts running within the SCEPTER framework will automatically fetch and load models based on the required dependency files, eliminating the need for manual downloads.
|
||||
We deploy a work studio on Modelscope that includes only the inference tab, please refer to [ms_scepter_studio](https://www.modelscope.cn/studios/damo/scepter_studio/summary) and [hf_scepter_studio](https://huggingface.co/spaces/modelscope/scepter_studio)
|
||||
|
||||
|
||||
## 🔍 Learn More
|
||||
@@ -396,6 +157,7 @@ PS: Scripts running within the SCEPTER framework will automatically fetch and lo
|
||||
|
||||
SWIFT (Scalable lightWeight Infrastructure for Fine-Tuning) is an extensible framwork designed to faciliate lightweight model fine-tuning and inference.
|
||||
|
||||
|
||||
## BibTeX
|
||||
If our work is useful for your research, please consider citing:
|
||||
```bibtex
|
||||
@@ -411,5 +173,6 @@ If our work is useful for your research, please consider citing:
|
||||
|
||||
This project is licensed under the [Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE).
|
||||
|
||||
|
||||
## Acknowledgement
|
||||
Thanks to [Stability-AI](https://github.com/Stability-AI), [SWIFT library](https://github.com/modelscope/swift/) and [Fooocus](https://github.com/lllyasviel/Fooocus) for their awesome work.
|
||||
Thanks to [Stability-AI](https://github.com/Stability-AI), [SWIFT library](https://github.com/modelscope/swift/) and [Fooocus](https://github.com/lllyasviel/Fooocus) for their awesome work.
|
||||
@@ -5,18 +5,18 @@ import os.path
|
||||
import random
|
||||
from collections import OrderedDict
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from PIL.Image import Image
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from scepter.modules.model.network.diffusion.diffusion import GaussianDiffusion
|
||||
from scepter.modules.model.network.diffusion.schedules import noise_schedule
|
||||
from scepter.modules.model.registry import (BACKBONES, EMBEDDERS, MODELS,
|
||||
TOKENIZERS)
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
|
||||
from scepter.studio.utils.env import get_available_memory
|
||||
|
||||
from .control_inference import ControlInference
|
||||
from .tuner_inference import TunerInference
|
||||
|
||||
|
||||
@@ -5,19 +5,19 @@ import os.path
|
||||
import random
|
||||
from collections import OrderedDict
|
||||
|
||||
from PIL.Image import Image
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
import torchvision.transforms.functional as TF
|
||||
from PIL.Image import Image
|
||||
|
||||
from scepter.modules.model.network.diffusion.diffusion import GaussianDiffusion
|
||||
from scepter.modules.model.network.diffusion.schedules import noise_schedule
|
||||
from scepter.modules.model.registry import (BACKBONES, EMBEDDERS, MODELS,
|
||||
TOKENIZERS)
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
from scepter.studio.utils.env import get_available_memory
|
||||
|
||||
from ...studio.utils.env import get_available_memory
|
||||
from .control_inference import ControlInference
|
||||
from .tuner_inference import TunerInference
|
||||
|
||||
|
||||
@@ -7,13 +7,9 @@ from scepter.modules.utils.file_system import FS
|
||||
|
||||
def download_image(image):
|
||||
if image is not None:
|
||||
client = FS.get_fs_client(image)
|
||||
if client.tmp_dir.startswith('/home'):
|
||||
name = get_md5(image)
|
||||
local_path = FS.get_from(image,
|
||||
f'/tmp/gradio/scepter_examples/{name}')
|
||||
else:
|
||||
local_path = FS.get_from(image)
|
||||
name = get_md5(image)
|
||||
local_path = FS.get_from(image,
|
||||
f'/tmp/gradio/scepter_examples/{name}')
|
||||
return local_path
|
||||
else:
|
||||
return image
|
||||
|
||||
@@ -12,6 +12,7 @@ from torchvision.utils import save_image
|
||||
|
||||
from scepter.modules.annotator.registry import ANNOTATORS
|
||||
from scepter.modules.inference.diffusion_inference import DiffusionInference
|
||||
from scepter.modules.inference.stylebooth_inference import StyleboothInference
|
||||
from scepter.modules.utils.config import Config
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
@@ -153,6 +154,21 @@ class DiffusionInferenceTest(unittest.TestCase):
|
||||
save_path = os.path.join(self.tmp_dir, 'sdxl_flower_canny.png')
|
||||
save_image(output['images'], save_path)
|
||||
|
||||
# @unittest.skip('')
|
||||
def test_stylebooth(self):
|
||||
config_file = 'scepter/methods/studio/inference/edit/stylebooth_tb_pro.yaml'
|
||||
cfg = Config(cfg_file=config_file)
|
||||
diff_infer = StyleboothInference(logger=self.logger)
|
||||
diff_infer.init_from_cfg(cfg)
|
||||
|
||||
output = diff_infer({'prompt': 'Let this image be in the style of sai-lowpoly'},
|
||||
style_edit_image=Image.open('asset/images/inpainting_text_ref/ex4_scene_im.jpg'),
|
||||
style_guide_scale_text=7.5,
|
||||
style_guide_scale_image=0.5)
|
||||
save_path = os.path.join(self.tmp_dir,
|
||||
'stylebooth_test_lowpoly_cute_dog.png')
|
||||
save_image(output['images'], save_path)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
unittest.main()
|
||||
|
||||