Compare commits
12
Commits
v1.1.0_dev
...
v1.2.0_dev
| Author | SHA1 | Date | |
|---|---|---|---|
 LouieStark |
aac85fa94f | ||
|
LouieStark
|
3f267aaea2 | ||
|
LouieStark
|
53357f95d6 | ||
|
LouieStark
|
cef93bdbfe | ||
|
LouieStark
|
b886400e06 | ||
|
LouieStark
|
f98adabeb3 | ||
|
LouieStark
|
fe3e11b49e | ||
|
LouieStark
|
e6b43f19f6 | ||
|
LouieStark
|
986349deac | ||
|
LouieStark
|
3f047be43c | ||
|
LouieStark
|
e8d8e63cba | ||
|
jiangzeyinzi
|
eac03e9856 |
+1
-2
@@ -9,13 +9,12 @@
|
||||
*.bin
|
||||
*.idea
|
||||
*.csv
|
||||
cache
|
||||
build
|
||||
dist
|
||||
dev
|
||||
scepter.egg-info
|
||||
.readthedocs.yml
|
||||
1.9
|
||||
#MANIFEST.in
|
||||
*resources
|
||||
*.ipynb_checkpoints*
|
||||
*.vscode
|
||||
|
||||
@@ -14,12 +14,13 @@ SCEPTER integrates popular community-driven implementations as well as proprieta
|
||||
SCEPTER offers 3 core components:
|
||||
- [Generative training and inference framework](#tutorials)
|
||||
- [Easy implementation of popular approaches](#currently-supported-approaches)
|
||||
- [Interactive user interface: SCEPTER Studio](#launch)
|
||||
- [Interactive user interface: SCEPTER Studio & Comfy UI](#launch)
|
||||
|
||||
|
||||
## 🎉 News
|
||||
- [🔥🔥🔥2024.10]: We are pleased to announce the release of the code for [ACE](https://arxiv.org/abs/2410.00086), supporting Customized Training / Comfy UI Workflow / gradio-based ChatBot Interface. The detailed documents can be found at [ACE repo](https://github.com/ali-vilab/ACE.git).
|
||||
- [2024.10]: Support for inference and tuning with [FLUX](https://huggingface.co/black-forest-labs/FLUX.1-dev), as well as for building [ComfyUI](https://github.com/comfyanonymous/ComfyUI) workflows using this framework.
|
||||
- [🔥2024.09]: We introduce **ACE**, an **A**ll-round **C**reator and **E**ditor adept at executing a diverse array of image editing tasks tailored to your specifications. Built upon the cutting-edge Diffusion Transformer architecture, ACE has been extensively trained on a comprehensive dataset to seamlessly interpret and execute any natural language instruction. For further information, please consult the [project page](https://ali-vilab.github.io/ace-page/).
|
||||
- [2024.09]: We introduce **ACE**, an **A**ll-round **C**reator and **E**ditor adept at executing a diverse array of image editing tasks tailored to your specifications. Built upon the cutting-edge Diffusion Transformer architecture, ACE has been extensively trained on a comprehensive dataset to seamlessly interpret and execute any natural language instruction. For further information, please consult the [project page](https://ali-vilab.github.io/ace-page/).
|
||||
- [2024.07]: Support the inference and training of open-source generative models based on the [DiT](https://arxiv.org/abs/2212.09748) architecture, such as [SD3](https://arxiv.org/pdf/2403.03206) and [PixArt](https://arxiv.org/abs/2310.00426).
|
||||
- [2024.05]: Introducing SCEPTER v1, supporting customized image edit tasks! Simply provide 10 image pairs, SCEPTER will tune an edit tuner for your own Image-to-Image tasks, like `Clay Style`, `De-Text`, `Segmentation`, etc.
|
||||
- [2024.04]: New [StyleBooth](https://ali-vilab.github.io/stylebooth-page/) demo on SCEPTER Studio for`Text-Based Style Editing`.
|
||||
@@ -33,13 +34,79 @@ SCEPTER offers 3 core components:
|
||||
|
||||
## 🖼 Gallery for Recent Works
|
||||
|
||||
### <img src="https://github.com/ali-vilab/ace-page/raw/main/static/images/logo.png?raw=true" height=20> <img src="https://github.com/ali-vilab/ace-page/raw/main/static/images/icon.png?raw=true" height=20>
|
||||
### ACE
|
||||
|
||||
ACE is a unified foundational model framework that supports a wide range of visual generation tasks. By defining CU for unifying multi-modal inputs across different tasks and incorporating long-
|
||||
context CU, we introduce historical contextual information into visual generation tasks, paving
|
||||
the way for ChatGPT-like dialog systems in visual generation.
|
||||
ACE is a unified foundational model framework that supports a wide range of visual generation tasks. By defining CU for unifying multi-modal inputs across different tasks and incorporating long-context CU, we introduce historical contextual information into visual generation tasks, paving the way for ChatGPT-like dialog systems in visual generation.
|
||||
|
||||
[](https://ali-vilab.github.io/ace-page/)
|
||||
[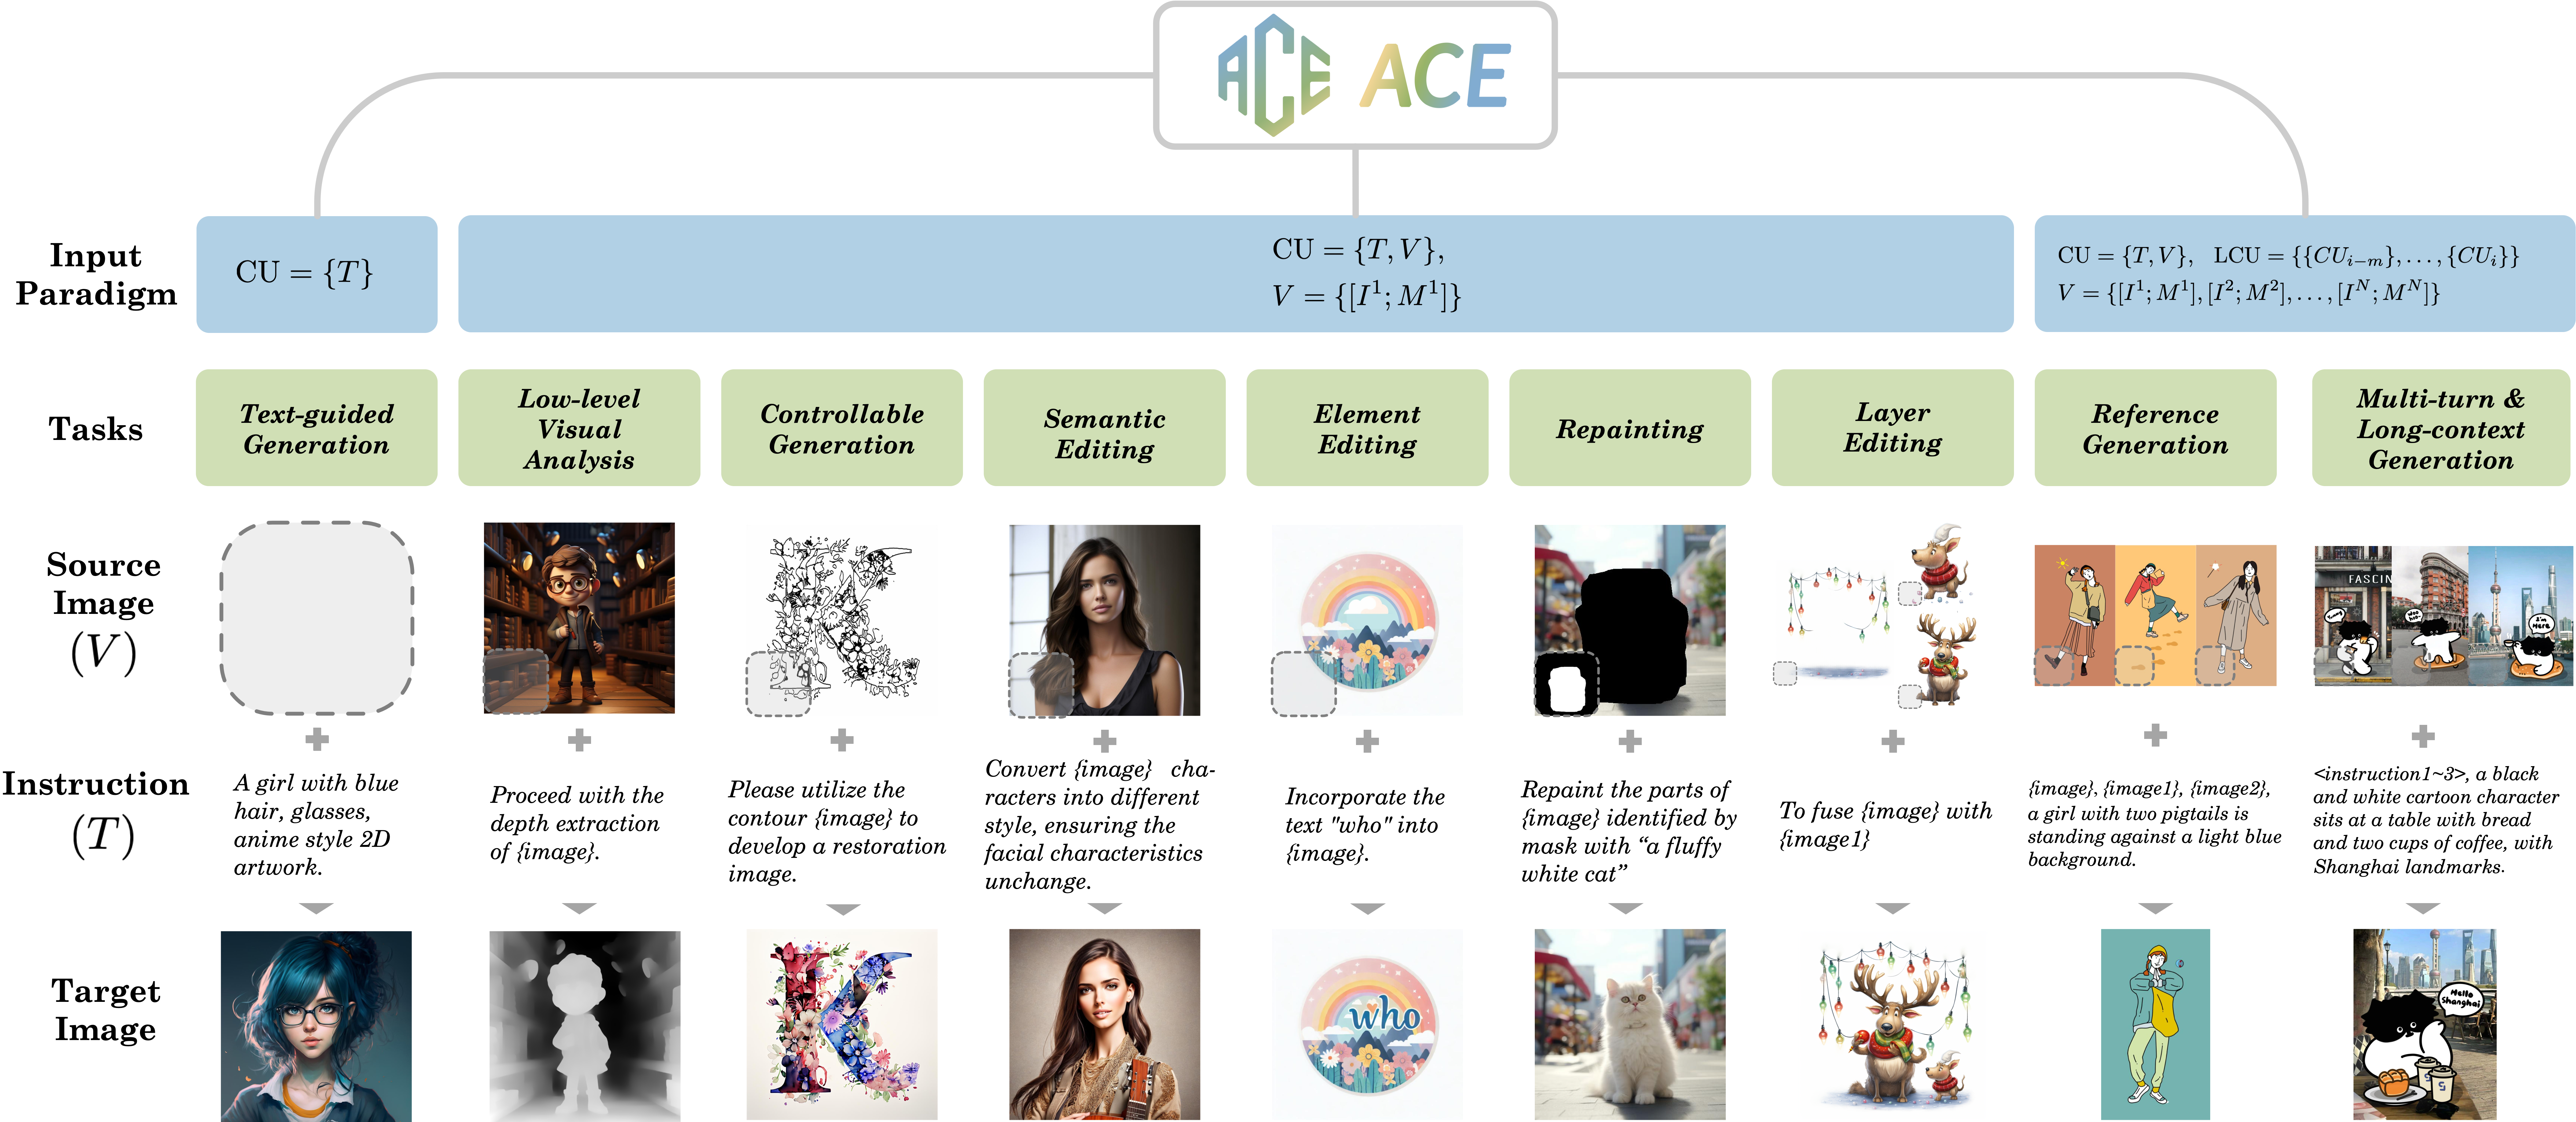](https://ali-vilab.github.io/ace-page/)
|
||||
|
||||
#### ACE Training
|
||||
|
||||
We offer a demonstration training YAML that enables the end-to-end training of ACE using a toy dataset. For a comprehensive overview of the hyperparameter configurations, please consult `scepter/methods/edit/dit_ace_0.6b_512.yaml`.
|
||||
|
||||
##### Prepare datasets
|
||||
|
||||
Please find the dataset class located in `scepter/modules/data/dataset/ms_dataset.py`,
|
||||
designed to facilitate end-to-end training using an open-source toy dataset.
|
||||
Download a dataset zip file from [modelscope](https://www.modelscope.cn/models/iic/scepter/resolve/master/datasets/hed_pair.zip), and then extract its contents into the `cache/datasets/` directory.
|
||||
|
||||
Should you wish to prepare your own datasets, we recommend consulting `scepter/modules/data/dataset/ms_dataset.py` for detailed guidance on the required data format.
|
||||
|
||||
##### Prepare initial weight
|
||||
The ACE checkpoint has been uploaded to both ModelScope and HuggingFace platforms:
|
||||
* [ModelScope](https://www.modelscope.cn/models/iic/ACE-0.6B-512px)
|
||||
* [HuggingFace](https://huggingface.co/scepter-studio/ACE-0.6B-512px)
|
||||
|
||||
In the provided training YAML configuration, we have designated the Modelscope URL as the default checkpoint URL. Should you wish to transition to Hugging Face, you can effortlessly achieve this by modifying the PRETRAINED_MODEL value within the YAML file (replace the prefix "ms://iic" to "hf://scepter-studio").
|
||||
|
||||
|
||||
##### Start training
|
||||
|
||||
You can easily start training procedure by executing the following command:
|
||||
```bash
|
||||
PYTHONPATH=. python scepter/tools/run_train.py --cfg scepter/methods/edit/dit_ace_0.6b_512.yaml
|
||||
```
|
||||
|
||||
#### ACE Chat Bot
|
||||
|
||||
We have developed a chatbot interface utilizing Gradio, designed to convert user input in natural language into visually captivating images that align semantically with the specified instructions. You can easily access this functionality by launching Scepter Studio with the following command:
|
||||
```bash
|
||||
PYTHONPATH=. python scepter/tools/webui.py --cfg scepter/methods/studio/scepter_ui.yaml --language zh
|
||||
```
|
||||
Upon starting, you will find a "ChatBot" tab within the Gradio application, which serves as a chat-based interface to handle any requests related to image editing or generation.
|
||||
|
||||
#### ACE ComfyUI Workflow
|
||||
|
||||

|
||||
|
||||
<table><tbody>
|
||||
<tr>
|
||||
<th align="center" colspan="4">ACE Workflow Examples</th>
|
||||
</tr>
|
||||
<tr>
|
||||
<th align="center" colspan="1">Control</th>
|
||||
<th align="center" colspan="1">Semantic</th>
|
||||
<th align="center" colspan="1">Element</th>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<a href="https://github.com/ali-vilab/ace-page/raw/main/assets/comfyui/ace_control.png" target="_blank">
|
||||
<img src="https://github.com/ali-vilab/ace-page/raw/main/assets/comfyui/ace_control.png" width="200">
|
||||
</a>
|
||||
</td>
|
||||
<td>
|
||||
<a href="https://github.com/ali-vilab/ace-page/raw/main/assets/comfyui/ace_semantic.png" target="_blank">
|
||||
<img src="https://github.com/ali-vilab/ace-page/raw/main/assets/comfyui/ace_semantic.png" width="200">
|
||||
</a>
|
||||
</td>
|
||||
<td>
|
||||
<a href="https://github.com/ali-vilab/ace-page/raw/main/assets/comfyui/ace_element.png" target="_blank">
|
||||
<img src="https://github.com/ali-vilab/ace-page/raw/main/assets/comfyui/ace_element.png" width="200">
|
||||
</a>
|
||||
</td>
|
||||
</tr>
|
||||
</tbody>
|
||||
</table>
|
||||
|
||||
### FLUX Tuners
|
||||
|
||||
@@ -154,7 +221,7 @@ pip install scepter
|
||||
| Controllable Image Synthesis | [🌟SCEdit(CVPR24)](docs/en/tasks/scedit.md) | [](https://arxiv.org/abs/2312.11392) [](https://scedit.github.io/) |
|
||||
| Image Editing | [🌟LAR-Gen](docs/en/tasks/largen.md) | [](https://arxiv.org/abs/2403.19534) [](https://ali-vilab.github.io/largen-page/) |
|
||||
| Image Editing | [🌟StyleBooth](docs/en/tasks/stylebooth.md) | [](https://arxiv.org/abs/2404.12154) [](https://ali-vilab.github.io/stylebooth-page/) |
|
||||
| Image Generation and Editing | [🌟ACE](https://ali-vilab.github.io/ace-page/) | [](https://arxiv.org/abs/2410.00086) [](https://ali-vilab.github.io/ace-page/) |
|
||||
| Image Generation and Editing | [🌟ACE](https://ali-vilab.github.io/ace-page/) | [](https://arxiv.org/abs/2410.00086) [](https://ali-vilab.github.io/ace-page/) [](https://huggingface.co/spaces/scepter-studio/ACE-Chat) <br> [](https://www.modelscope.cn/models/iic/ACE-0.6B-512px) [](https://huggingface.co/scepter-studio/ACE-0.6B-512px) |
|
||||
|
||||
|
||||
## 🖥️ SCEPTER Studio
|
||||
@@ -201,7 +268,7 @@ cp -r path/to/scepter/workflow/ path/to/ComfyUI/custom_nodes/ComfyUI-Scepter
|
||||
cd path/to/ComfyUI
|
||||
python main.py
|
||||
```
|
||||
Alternatively, we will support ComfyUI Manager shortly.
|
||||
In addition, we also support installation and usage through the ComfyUI Manager.
|
||||
|
||||
|
||||
## 🔍 Learn More
|
||||
|
||||
@@ -1,5 +1,6 @@
|
||||
bitsandbytes
|
||||
gradio
|
||||
gradio==4.44.1
|
||||
gradio_imageslider
|
||||
imagehash
|
||||
psutil
|
||||
tiktoken
|
||||
|
||||
@@ -0,0 +1,161 @@
|
||||
ENV:
|
||||
BACKEND: nccl
|
||||
SEED: 2024
|
||||
#
|
||||
SOLVER:
|
||||
NAME: ACESolver
|
||||
RESUME_FROM:
|
||||
LOAD_MODEL_ONLY: True
|
||||
USE_FSDP: False
|
||||
SHARDING_STRATEGY:
|
||||
USE_AMP: True
|
||||
DTYPE: float16
|
||||
CHANNELS_LAST: True
|
||||
MAX_STEPS: 500
|
||||
MAX_EPOCHS: -1
|
||||
NUM_FOLDS: 1
|
||||
ACCU_STEP: 1
|
||||
EVAL_INTERVAL: 50
|
||||
RESCALE_LR: False
|
||||
#
|
||||
WORK_DIR: ./cache/save_data/ace_0.6b_512
|
||||
LOG_FILE: std_log.txt
|
||||
#
|
||||
FILE_SYSTEM:
|
||||
- NAME: "HuggingfaceFs"
|
||||
TEMP_DIR: ./cache/cache_data
|
||||
- NAME: "LocalFs"
|
||||
TEMP_DIR: ./cache/cache_data
|
||||
- NAME: "ModelscopeFs"
|
||||
TEMP_DIR: ./cache/cache_data
|
||||
|
||||
#
|
||||
MODEL:
|
||||
NAME: LatentDiffusionACE
|
||||
PRETRAINED_MODEL:
|
||||
IGNORE_KEYS: [ ]
|
||||
SCALE_FACTOR: 0.18215
|
||||
SIZE_FACTOR: 8
|
||||
DECODER_BIAS: 0.5
|
||||
DEFAULT_N_PROMPT:
|
||||
USE_EMA: True
|
||||
EVAL_EMA: False
|
||||
TEXT_IDENTIFIER: [ '{image}', '{image1}', '{image2}', '{image3}', '{image4}', '{image5}', '{image6}', '{image7}', '{image8}', '{image9}' ]
|
||||
USE_TEXT_POS_EMBEDDINGS: True
|
||||
#
|
||||
DIFFUSION:
|
||||
NAME: BaseDiffusion
|
||||
PREDICTION_TYPE: eps
|
||||
MIN_SNR_GAMMA:
|
||||
NOISE_SCHEDULER:
|
||||
NAME: LinearScheduler
|
||||
NUM_TIMESTEPS: 1000
|
||||
BETA_MIN: 0.0001
|
||||
BETA_MAX: 0.02
|
||||
#
|
||||
DIFFUSION_MODEL:
|
||||
NAME: ACE
|
||||
PRETRAINED_MODEL: ms://iic/ACE-0.6B-512px@models/dit/ace_0.6b_512px.pth
|
||||
IGNORE_KEYS: [ ]
|
||||
PATCH_SIZE: 2
|
||||
IN_CHANNELS: 4
|
||||
HIDDEN_SIZE: 1152
|
||||
DEPTH: 28
|
||||
NUM_HEADS: 16
|
||||
MLP_RATIO: 4.0
|
||||
PRED_SIGMA: True
|
||||
DROP_PATH: 0.0
|
||||
WINDOW_DIZE: 0
|
||||
Y_CHANNELS: 4096
|
||||
MAX_SEQ_LEN: 1024
|
||||
QK_NORM: True
|
||||
USE_GRAD_CHECKPOINT: True
|
||||
ATTENTION_BACKEND: flash_attn
|
||||
#
|
||||
FIRST_STAGE_MODEL:
|
||||
NAME: AutoencoderKL
|
||||
EMBED_DIM: 4
|
||||
PRETRAINED_MODEL: ms://iic/ACE-0.6B-512px@models/vae/vae.bin
|
||||
IGNORE_KEYS: []
|
||||
#
|
||||
ENCODER:
|
||||
NAME: Encoder
|
||||
CH: 128
|
||||
OUT_CH: 3
|
||||
NUM_RES_BLOCKS: 2
|
||||
IN_CHANNELS: 3
|
||||
ATTN_RESOLUTIONS: [ ]
|
||||
CH_MULT: [ 1, 2, 4, 4 ]
|
||||
Z_CHANNELS: 4
|
||||
DOUBLE_Z: True
|
||||
DROPOUT: 0.0
|
||||
RESAMP_WITH_CONV: True
|
||||
#
|
||||
DECODER:
|
||||
NAME: Decoder
|
||||
CH: 128
|
||||
OUT_CH: 3
|
||||
NUM_RES_BLOCKS: 2
|
||||
IN_CHANNELS: 3
|
||||
ATTN_RESOLUTIONS: [ ]
|
||||
CH_MULT: [ 1, 2, 4, 4 ]
|
||||
Z_CHANNELS: 4
|
||||
DROPOUT: 0.0
|
||||
RESAMP_WITH_CONV: True
|
||||
GIVE_PRE_END: False
|
||||
TANH_OUT: False
|
||||
#
|
||||
COND_STAGE_MODEL:
|
||||
NAME: T5EmbedderHF
|
||||
PRETRAINED_MODEL: ms://iic/ACE-0.6B-512px@models/text_encoder/t5-v1_1-xxl/
|
||||
TOKENIZER_PATH: ms://iic/ACE-0.6B-512px@models/tokenizer/t5-v1_1-xxl
|
||||
LENGTH: 120
|
||||
T5_DTYPE: bfloat16
|
||||
ADDED_IDENTIFIER: [ '{image}', '{caption}', '{mask}', '{ref_image}', '{image1}', '{image2}', '{image3}', '{image4}', '{image5}', '{image6}', '{image7}', '{image8}', '{image9}' ]
|
||||
CLEAN: whitespace
|
||||
USE_GRAD: False
|
||||
LOSS:
|
||||
NAME: ReconstructLoss
|
||||
LOSS_TYPE: l2
|
||||
#
|
||||
SAMPLE_ARGS:
|
||||
SAMPLER: ddim
|
||||
SAMPLE_STEPS: 20
|
||||
GUIDE_SCALE: 4.5
|
||||
GUIDE_RESCALE: 0.5
|
||||
#
|
||||
OPTIMIZER:
|
||||
NAME: AdamW
|
||||
LEARNING_RATE: 1e-7
|
||||
EPS: 1e-10
|
||||
WEIGHT_DECAY: 5e-4
|
||||
#
|
||||
TRAIN_DATA:
|
||||
NAME: ImageTextPairMSDatasetForACE
|
||||
MODE: train
|
||||
MS_DATASET_NAME: cache/datasets/hed_pair
|
||||
MS_DATASET_NAMESPACE: ""
|
||||
MS_DATASET_SPLIT: "train"
|
||||
MS_DATASET_SUBNAME: ""
|
||||
PROMPT_PREFIX: ""
|
||||
REPLACE_STYLE: False
|
||||
MAX_SEQ_LEN: 1024
|
||||
PIN_MEMORY: True
|
||||
BATCH_SIZE: 1
|
||||
NUM_WORKERS: 1
|
||||
SAMPLER:
|
||||
NAME: LoopSampler
|
||||
#
|
||||
TRAIN_HOOKS:
|
||||
-
|
||||
NAME: BackwardHook
|
||||
PRIORITY: 0
|
||||
-
|
||||
NAME: LogHook
|
||||
LOG_INTERVAL: 50
|
||||
-
|
||||
NAME: CheckpointHook
|
||||
INTERVAL: 100
|
||||
-
|
||||
NAME: ProbeDataHook
|
||||
PROB_INTERVAL: 100
|
||||
@@ -0,0 +1,25 @@
|
||||
WORK_DIR: chatbot
|
||||
FILE_SYSTEM:
|
||||
- NAME: LocalFs
|
||||
TEMP_DIR: ./cache/cache_data
|
||||
- NAME: ModelscopeFs
|
||||
TEMP_DIR: ./cache/cache_data
|
||||
- NAME: HuggingfaceFs
|
||||
TEMP_DIR: ./cache/cache_data
|
||||
#
|
||||
ENABLE_I2V: False
|
||||
#
|
||||
MODEL:
|
||||
EDIT_MODEL:
|
||||
MODEL_CFG_DIR: scepter/methods/studio/chatbot/models/
|
||||
DEFAULT: ace_0.6b_512
|
||||
I2V:
|
||||
MODEL_NAME: CogVideoX-5b-I2V
|
||||
MODEL_DIR: ms://ZhipuAI/CogVideoX-5b-I2V/
|
||||
CAPTIONER:
|
||||
MODEL_NAME: InternVL2-2B
|
||||
MODEL_DIR: ms://OpenGVLab/InternVL2-2B/
|
||||
PROMPT: '<image>\nThis image is the first frame of a video. Based on this image, please imagine what changes may occur in the next few seconds of the video. Please output brief description, such as "a dog running" or "a person turns to left". No more than 30 words.'
|
||||
ENHANCER:
|
||||
MODEL_NAME: Meta-Llama-3.1-8B-Instruct
|
||||
MODEL_DIR: ms://LLM-Research/Meta-Llama-3.1-8B-Instruct/
|
||||
@@ -0,0 +1,127 @@
|
||||
NAME: ACE_0.6B_512
|
||||
IS_DEFAULT: False
|
||||
DEFAULT_PARAS:
|
||||
PARAS:
|
||||
#
|
||||
INPUT:
|
||||
INPUT_IMAGE:
|
||||
INPUT_MASK:
|
||||
TASK:
|
||||
PROMPT: ""
|
||||
NEGATIVE_PROMPT: ""
|
||||
OUTPUT_HEIGHT: 512
|
||||
OUTPUT_WIDTH: 512
|
||||
SAMPLER: ddim
|
||||
SAMPLE_STEPS: 20
|
||||
GUIDE_SCALE: 4.5
|
||||
GUIDE_RESCALE: 0.5
|
||||
SEED: -1
|
||||
TAR_INDEX: 0
|
||||
OUTPUT:
|
||||
LATENT:
|
||||
IMAGES:
|
||||
SEED:
|
||||
MODULES_PARAS:
|
||||
FIRST_STAGE_MODEL:
|
||||
FUNCTION:
|
||||
- NAME: encode
|
||||
DTYPE: float16
|
||||
INPUT: ["IMAGE"]
|
||||
- NAME: decode
|
||||
DTYPE: float16
|
||||
INPUT: ["LATENT"]
|
||||
#
|
||||
DIFFUSION_MODEL:
|
||||
FUNCTION:
|
||||
- NAME: forward
|
||||
DTYPE: float16
|
||||
INPUT: ["SAMPLE_STEPS", "SAMPLE", "GUIDE_SCALE"]
|
||||
#
|
||||
COND_STAGE_MODEL:
|
||||
FUNCTION:
|
||||
- NAME: encode_list
|
||||
DTYPE: bfloat16
|
||||
INPUT: ["PROMPT"]
|
||||
#
|
||||
MODEL:
|
||||
NAME: LatentDiffusionACE
|
||||
PRETRAINED_MODEL:
|
||||
IGNORE_KEYS: [ ]
|
||||
SCALE_FACTOR: 0.18215
|
||||
SIZE_FACTOR: 8
|
||||
DECODER_BIAS: 0.5
|
||||
DEFAULT_N_PROMPT: ""
|
||||
TEXT_IDENTIFIER: [ '{image}', '{image1}', '{image2}', '{image3}', '{image4}', '{image5}', '{image6}', '{image7}', '{image8}', '{image9}' ]
|
||||
USE_TEXT_POS_EMBEDDINGS: True
|
||||
#
|
||||
DIFFUSION:
|
||||
NAME: BaseDiffusion
|
||||
PREDICTION_TYPE: eps
|
||||
MIN_SNR_GAMMA:
|
||||
NOISE_SCHEDULER:
|
||||
NAME: LinearScheduler
|
||||
NUM_TIMESTEPS: 1000
|
||||
BETA_MIN: 0.0001
|
||||
BETA_MAX: 0.02
|
||||
#
|
||||
DIFFUSION_MODEL:
|
||||
NAME: ACE
|
||||
PRETRAINED_MODEL: ms://iic/ACE-0.6B-512px@models/dit/ace_0.6b_512px.pth
|
||||
IGNORE_KEYS: [ ]
|
||||
PATCH_SIZE: 2
|
||||
IN_CHANNELS: 4
|
||||
HIDDEN_SIZE: 1152
|
||||
DEPTH: 28
|
||||
NUM_HEADS: 16
|
||||
MLP_RATIO: 4.0
|
||||
PRED_SIGMA: True
|
||||
DROP_PATH: 0.0
|
||||
WINDOW_DIZE: 0
|
||||
Y_CHANNELS: 4096
|
||||
MAX_SEQ_LEN: 1024
|
||||
QK_NORM: True
|
||||
USE_GRAD_CHECKPOINT: True
|
||||
ATTENTION_BACKEND: flash_attn
|
||||
#
|
||||
FIRST_STAGE_MODEL:
|
||||
NAME: AutoencoderKL
|
||||
EMBED_DIM: 4
|
||||
PRETRAINED_MODEL: ms://iic/ACE-0.6B-512px@models/vae/vae.bin
|
||||
IGNORE_KEYS: []
|
||||
#
|
||||
ENCODER:
|
||||
NAME: Encoder
|
||||
CH: 128
|
||||
OUT_CH: 3
|
||||
NUM_RES_BLOCKS: 2
|
||||
IN_CHANNELS: 3
|
||||
ATTN_RESOLUTIONS: [ ]
|
||||
CH_MULT: [ 1, 2, 4, 4 ]
|
||||
Z_CHANNELS: 4
|
||||
DOUBLE_Z: True
|
||||
DROPOUT: 0.0
|
||||
RESAMP_WITH_CONV: True
|
||||
#
|
||||
DECODER:
|
||||
NAME: Decoder
|
||||
CH: 128
|
||||
OUT_CH: 3
|
||||
NUM_RES_BLOCKS: 2
|
||||
IN_CHANNELS: 3
|
||||
ATTN_RESOLUTIONS: [ ]
|
||||
CH_MULT: [ 1, 2, 4, 4 ]
|
||||
Z_CHANNELS: 4
|
||||
DROPOUT: 0.0
|
||||
RESAMP_WITH_CONV: True
|
||||
GIVE_PRE_END: False
|
||||
TANH_OUT: False
|
||||
#
|
||||
COND_STAGE_MODEL:
|
||||
NAME: T5EmbedderHF
|
||||
PRETRAINED_MODEL: ms://iic/ACE-0.6B-512px@models/text_encoder/t5-v1_1-xxl/
|
||||
TOKENIZER_PATH: ms://iic/ACE-0.6B-512px@models/tokenizer/t5-v1_1-xxl
|
||||
LENGTH: 120
|
||||
T5_DTYPE: bfloat16
|
||||
ADDED_IDENTIFIER: [ '{image}', '{caption}', '{mask}', '{ref_image}', '{image1}', '{image2}', '{image3}', '{image4}', '{image5}', '{image6}', '{image7}', '{image8}', '{image9}' ]
|
||||
CLEAN: whitespace
|
||||
USE_GRAD: False
|
||||
@@ -87,3 +87,7 @@ INTERFACE:
|
||||
NAME_EN: Inference
|
||||
IFID: inference
|
||||
CONFIG: scepter/methods/studio/inference/inference.yaml
|
||||
- NAME: 对话式编辑
|
||||
NAME_EN: ChatBot
|
||||
IFID: ChatBot
|
||||
CONFIG: scepter/methods/studio/chatbot/chatbot.yaml
|
||||
|
||||
@@ -1,20 +1,11 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
import math
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from abc import ABCMeta
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
import torchvision.transforms as TT
|
||||
from einops import rearrange
|
||||
from scepter.modules.annotator.base_annotator import BaseAnnotator
|
||||
from scepter.modules.annotator.registry import ANNOTATORS
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
|
||||
|
||||
@ANNOTATORS.register_class()
|
||||
|
||||
@@ -2,20 +2,17 @@
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from abc import ABCMeta
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torchvision
|
||||
import torchvision.transforms as transforms
|
||||
from einops import rearrange
|
||||
from PIL import Image
|
||||
from torchvision.transforms import InterpolationMode
|
||||
|
||||
from scepter.modules.annotator.base_annotator import BaseAnnotator
|
||||
from scepter.modules.annotator.registry import ANNOTATORS
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
from torchvision.transforms import InterpolationMode
|
||||
|
||||
norm_layer = nn.InstanceNorm2d
|
||||
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import math
|
||||
import random
|
||||
from abc import ABCMeta
|
||||
from enum import Enum
|
||||
@@ -8,7 +7,8 @@ from enum import Enum
|
||||
import cv2
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import Image, ImageDraw
|
||||
from PIL import Image
|
||||
|
||||
from scepter.modules.annotator.base_annotator import BaseAnnotator
|
||||
from scepter.modules.annotator.registry import ANNOTATORS
|
||||
from scepter.modules.utils.config import Config, dict_to_yaml
|
||||
@@ -226,7 +226,12 @@ class InpaintingAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
||||
self.return_invert = cfg.get('RETURN_INVERT', True)
|
||||
self.mask_color = cfg.get('MASK_COLOR', 0)
|
||||
|
||||
def forward(self, image, mask=None, return_mask=None, return_invert=None, mask_color=None):
|
||||
def forward(self,
|
||||
image,
|
||||
mask=None,
|
||||
return_mask=None,
|
||||
return_invert=None,
|
||||
mask_color=None):
|
||||
return_mask = return_mask if return_mask is not None else self.return_mask
|
||||
return_invert = return_invert if return_invert is not None else self.return_invert
|
||||
mask_color = mask_color if mask_color is not None else self.mask_color
|
||||
@@ -247,18 +252,17 @@ class InpaintingAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
||||
else:
|
||||
img = np.transpose(image, (2, 0, 1))
|
||||
mask = self.mask_generator(img)
|
||||
mask = (np.transpose(mask, (1, 2, 0)).squeeze(-1) * 255).astype(np.uint8)
|
||||
mask = (np.transpose(mask,
|
||||
(1, 2, 0)).squeeze(-1) * 255).astype(np.uint8)
|
||||
if return_invert:
|
||||
mask = invert_image(mask)
|
||||
colored_mask = np.zeros_like(image)
|
||||
if mask_color: colored_mask[:] = mask_color
|
||||
image = np.where(mask[:, :, np.newaxis] == 255, colored_mask, image)
|
||||
image = np.where(mask[:, :, np.newaxis] == 255, colored_mask,
|
||||
image)
|
||||
|
||||
if return_mask:
|
||||
ret_data = {
|
||||
'image': np.array(image),
|
||||
'mask': np.array(mask)
|
||||
}
|
||||
ret_data = {'image': np.array(image), 'mask': np.array(mask)}
|
||||
else:
|
||||
ret_data = np.array(image)
|
||||
return ret_data
|
||||
|
||||
@@ -1,27 +1,31 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from abc import ABCMeta
|
||||
|
||||
import torch
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
import cv2
|
||||
import torch
|
||||
from PIL import Image
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.annotator.base_annotator import BaseAnnotator
|
||||
from scepter.modules.annotator.registry import ANNOTATORS
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
|
||||
|
||||
def dilate_mask(mask, dilate_factor=15):
|
||||
mask = mask.astype(np.uint8)
|
||||
mask = cv2.dilate(
|
||||
mask,
|
||||
np.ones((dilate_factor, dilate_factor), np.uint8),
|
||||
iterations=1
|
||||
)
|
||||
mask = cv2.dilate(mask,
|
||||
np.ones((dilate_factor, dilate_factor), np.uint8),
|
||||
iterations=1)
|
||||
return mask
|
||||
|
||||
|
||||
@ANNOTATORS.register_class()
|
||||
class LamaAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
||||
para_dict = {}
|
||||
|
||||
def __init__(self, cfg, logger=None):
|
||||
super().__init__(cfg, logger=logger)
|
||||
from modelscope.pipelines.builder import PIPELINES
|
||||
@@ -32,26 +36,29 @@ class LamaAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
||||
from modelscope.models.cv.image_inpainting.refinement import refine_predict
|
||||
from torch.utils.data._utils.collate import default_collate
|
||||
|
||||
@PIPELINES.register_module(Tasks.image_inpainting, module_name=Pipelines.image_inpainting + "-v2")
|
||||
@PIPELINES.register_module(Tasks.image_inpainting,
|
||||
module_name=Pipelines.image_inpainting +
|
||||
'-v2')
|
||||
class ImageInpaintingPipelineV2(ImageInpaintingPipeline):
|
||||
def perform_inference(self, data):
|
||||
px_budget = 9000000
|
||||
batch = default_collate([data])
|
||||
if self.refine:
|
||||
assert 'unpad_to_size' in batch, 'Unpadded size is required for the refinement'
|
||||
assert 'cuda' in str(self.device), 'GPU is required for refinement'
|
||||
assert 'cuda' in str(
|
||||
self.device), 'GPU is required for refinement'
|
||||
gpu_ids = str(self.device).split(':')[-1]
|
||||
cur_res = refine_predict(
|
||||
batch,
|
||||
self.infer_model,
|
||||
gpu_ids=gpu_ids,
|
||||
modulo=self.pad_out_to_modulo,
|
||||
n_iters=15,
|
||||
lr=0.002,
|
||||
min_side=512,
|
||||
max_scales=3,
|
||||
px_budget=px_budget)
|
||||
cur_res = cur_res[0].permute(1, 2, 0).detach().cpu().numpy()
|
||||
cur_res = refine_predict(batch,
|
||||
self.infer_model,
|
||||
gpu_ids=gpu_ids,
|
||||
modulo=self.pad_out_to_modulo,
|
||||
n_iters=15,
|
||||
lr=0.002,
|
||||
min_side=512,
|
||||
max_scales=3,
|
||||
px_budget=px_budget)
|
||||
cur_res = cur_res[0].permute(1, 2,
|
||||
0).detach().cpu().numpy()
|
||||
else:
|
||||
with torch.no_grad():
|
||||
batch = self.move_to_device(batch, self.device)
|
||||
@@ -69,9 +76,13 @@ class LamaAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
||||
return cur_res
|
||||
|
||||
lama_model_dir = FS.get_dir_to_local_dir(cfg.PRETRAINED_MODEL)
|
||||
self.lama_model = pipeline(Tasks.image_inpainting, model=lama_model_dir,
|
||||
pipeline_name=Pipelines.image_inpainting + "-v2", refine=True,
|
||||
device="cuda:{}".format(we.device_id))
|
||||
self.lama_model = pipeline(Tasks.image_inpainting,
|
||||
model=lama_model_dir,
|
||||
pipeline_name=Pipelines.image_inpainting +
|
||||
'-v2',
|
||||
refine=True,
|
||||
device='cuda:{}'.format(we.device_id))
|
||||
|
||||
def forward(self, image, mask):
|
||||
mask = dilate_mask(mask, dilate_factor=19)
|
||||
input_mask = Image.fromarray(mask)
|
||||
@@ -93,6 +104,3 @@ class LamaAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
||||
__class__.__name__,
|
||||
LamaAnnotator.para_dict,
|
||||
set_name=True)
|
||||
|
||||
|
||||
|
||||
|
||||
@@ -789,7 +789,7 @@ class OpenposeAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
||||
raise f'Unsurpport datatype{type(image)}, only surpport np.ndarray, torch.Tensor, Pillow Image.'
|
||||
image = image[:, :, ::-1]
|
||||
candidate, subset = self.body_estimation(image)
|
||||
canvas = np.zeros_like(image)
|
||||
canvas = np.zeros_like(image, order='C') # to check
|
||||
canvas = draw_bodypose(canvas, candidate, subset)
|
||||
if self.use_hand:
|
||||
hands_list = handDetect(candidate, subset, image)
|
||||
|
||||
@@ -4,10 +4,10 @@ import math
|
||||
import random
|
||||
from abc import ABCMeta
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import Image, ImageDraw
|
||||
|
||||
from scepter.modules.annotator.base_annotator import BaseAnnotator
|
||||
from scepter.modules.annotator.registry import ANNOTATORS
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
@@ -87,7 +87,8 @@ class OutpaintingAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
||||
if down > 0:
|
||||
down = tar_height - src_height - up
|
||||
if mask_color is not None:
|
||||
img = Image.new('RGB', (tar_width, tar_height), color=mask_color)
|
||||
img = Image.new('RGB', (tar_width, tar_height),
|
||||
color=mask_color)
|
||||
else:
|
||||
img = Image.new('RGB', (tar_width, tar_height))
|
||||
img.paste(init_image, (left, up))
|
||||
@@ -108,20 +109,30 @@ class OutpaintingAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
||||
init_image = image
|
||||
else:
|
||||
mask = Image.new('L', (image.width, image.height), 'white')
|
||||
mask_zero = Image.new('L', (bbox[2]-bbox[0], bbox[3]-bbox[1]), 'black')
|
||||
mask_zero = Image.new('L',
|
||||
(bbox[2] - bbox[0], bbox[3] - bbox[1]),
|
||||
'black')
|
||||
mask.paste(mask_zero, (bbox[0], bbox[1]))
|
||||
crop_image = image.crop(bbox)
|
||||
init_image = Image.new('RGB', (image.width, image.height), 'black')
|
||||
init_image = Image.new('RGB', (image.width, image.height),
|
||||
'black')
|
||||
init_image.paste(crop_image, (bbox[0], bbox[1]))
|
||||
img = image
|
||||
if return_mask:
|
||||
if return_source:
|
||||
ret_data = {'src_image': np.array(init_image), 'image': np.array(img), 'mask': np.array(mask)}
|
||||
ret_data = {
|
||||
'src_image': np.array(init_image),
|
||||
'image': np.array(img),
|
||||
'mask': np.array(mask)
|
||||
}
|
||||
else:
|
||||
ret_data = {'image': np.array(img), 'mask': np.array(mask)}
|
||||
else:
|
||||
if return_source:
|
||||
ret_data = {'src_image': np.array(init_image), 'image': np.array(img)}
|
||||
ret_data = {
|
||||
'src_image': np.array(init_image),
|
||||
'image': np.array(img)
|
||||
}
|
||||
else:
|
||||
ret_data = np.array(img)
|
||||
return ret_data
|
||||
@@ -133,6 +144,7 @@ class OutpaintingAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
||||
OutpaintingAnnotator.para_dict,
|
||||
set_name=True)
|
||||
|
||||
|
||||
@ANNOTATORS.register_class()
|
||||
class OutpaintingResize(BaseAnnotator, metaclass=ABCMeta):
|
||||
para_dict = {}
|
||||
@@ -148,11 +160,7 @@ class OutpaintingResize(BaseAnnotator, metaclass=ABCMeta):
|
||||
top, bottom = np.min(locs[0]), np.max(locs[0])
|
||||
return [left, top, right, bottom]
|
||||
|
||||
def forward(self,
|
||||
image,
|
||||
target_image,
|
||||
mask=None
|
||||
):
|
||||
def forward(self, image, target_image, mask=None):
|
||||
if isinstance(image, Image.Image):
|
||||
image = image
|
||||
elif isinstance(image, torch.Tensor):
|
||||
@@ -175,8 +183,10 @@ class OutpaintingResize(BaseAnnotator, metaclass=ABCMeta):
|
||||
if bbox is None:
|
||||
init_image = image
|
||||
else:
|
||||
paste_img = image.resize((bbox[2]-bbox[0], bbox[3]-bbox[1]))
|
||||
init_image = Image.new('RGB', (target_image.width, target_image.height), 'black')
|
||||
paste_img = image.resize((bbox[2] - bbox[0], bbox[3] - bbox[1]))
|
||||
init_image = Image.new('RGB',
|
||||
(target_image.width, target_image.height),
|
||||
'black')
|
||||
init_image.paste(paste_img, (bbox[0], bbox[1]))
|
||||
ret_data = {'src_image': np.array(init_image)}
|
||||
return ret_data
|
||||
|
||||
@@ -1,14 +1,13 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import math
|
||||
from abc import ABCMeta
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
import torchvision.transforms as TT
|
||||
from einops import rearrange
|
||||
from scepter.modules.annotator.base_annotator import BaseAnnotator
|
||||
from scepter.modules.annotator.registry import ANNOTATORS
|
||||
|
||||
@@ -15,7 +15,7 @@ def build_annotator(cfg, registry, logger=None, *args, **kwargs):
|
||||
raise TypeError(f'Config must be type dict, got {type(cfg)}')
|
||||
if cfg.have('PRETRAINED_MODEL'):
|
||||
pretrain_cfg = cfg.PRETRAINED_MODEL
|
||||
if pretrain_cfg is not None and not isinstance(pretrain_cfg, (str)):
|
||||
if pretrain_cfg is not None and not isinstance(pretrain_cfg, (str, list)):
|
||||
raise TypeError('Pretrain parameter must be a string')
|
||||
else:
|
||||
pretrain_cfg = None
|
||||
|
||||
@@ -1,6 +1,5 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import math
|
||||
import random
|
||||
from abc import ABCMeta
|
||||
|
||||
@@ -9,15 +8,16 @@ import numpy as np
|
||||
import torch
|
||||
import torchvision.transforms as T
|
||||
from PIL import Image
|
||||
from scipy import ndimage
|
||||
from pycocotools import mask as mask_utils
|
||||
from scipy import ndimage
|
||||
from sklearn.cluster import KMeans
|
||||
from torchvision.ops.boxes import batched_nms
|
||||
|
||||
from scepter.modules.annotator.base_annotator import BaseAnnotator
|
||||
from scepter.modules.annotator.registry import ANNOTATORS
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
from sklearn.cluster import KMeans
|
||||
from torchvision.ops.boxes import batched_nms
|
||||
|
||||
|
||||
def find_dominant_color(image, k=1):
|
||||
@@ -28,7 +28,7 @@ def find_dominant_color(image, k=1):
|
||||
kmeans = KMeans(n_clusters=k, n_init='auto')
|
||||
kmeans.fit(pixels)
|
||||
dominant_color = kmeans.cluster_centers_.astype(int)[0]
|
||||
except:
|
||||
except Exception:
|
||||
dominant_color = np.array([255, 255, 255])
|
||||
return dominant_color
|
||||
|
||||
@@ -62,16 +62,9 @@ class ESAMAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
||||
super().__init__(cfg, logger=logger)
|
||||
try:
|
||||
from efficient_sam.efficient_sam import build_efficient_sam
|
||||
from segment_anything.utils.amg import (
|
||||
batched_mask_to_box,
|
||||
calculate_stability_score,
|
||||
mask_to_rle_pytorch,
|
||||
remove_small_regions,
|
||||
rle_to_mask,
|
||||
)
|
||||
except:
|
||||
except Exception:
|
||||
raise NotImplementedError(
|
||||
f'Please install efficient_sam and segment_anything modules.')
|
||||
'Please install efficient_sam and segment_anything modules.')
|
||||
|
||||
pretrained_model = cfg.get('PRETRAINED_MODEL', None)
|
||||
if pretrained_model:
|
||||
@@ -294,8 +287,6 @@ class ESAMAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
||||
set_name=True)
|
||||
|
||||
|
||||
|
||||
|
||||
@ANNOTATORS.register_class()
|
||||
class SAMAnnotatorDraw(BaseAnnotator, metaclass=ABCMeta):
|
||||
para_dict = {}
|
||||
@@ -312,10 +303,16 @@ class SAMAnnotatorDraw(BaseAnnotator, metaclass=ABCMeta):
|
||||
|
||||
if pretrained_model:
|
||||
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
||||
seg_model = sam_model_registry[self.sam_model](checkpoint=local_path).eval().to(we.device_id)
|
||||
seg_model = sam_model_registry[self.sam_model](
|
||||
checkpoint=local_path).eval().to(we.device_id)
|
||||
self.sam_predictor = SamPredictor(seg_model)
|
||||
|
||||
def forward(self, image, input_box=None, mask=None, task_type=None, multimask_output=False):
|
||||
def forward(self,
|
||||
image,
|
||||
input_box=None,
|
||||
mask=None,
|
||||
task_type=None,
|
||||
multimask_output=False):
|
||||
task_type = task_type if task_type is not None else self.task_type
|
||||
|
||||
if isinstance(image, Image.Image):
|
||||
@@ -337,21 +334,25 @@ class SAMAnnotatorDraw(BaseAnnotator, metaclass=ABCMeta):
|
||||
else:
|
||||
raise f'Unsurpport datatype{type(mask)}, only surpport np.ndarray, torch.Tensor, Pillow Image.'
|
||||
|
||||
original_size = image.shape[:2]
|
||||
if task_type == 'mask_point':
|
||||
scribble = mask.transpose(2, 1, 0)[0]
|
||||
labeled_array, num_features = ndimage.label(scribble >= 255)
|
||||
centers = ndimage.center_of_mass(scribble, labeled_array, range(1, num_features + 1))
|
||||
centers = ndimage.center_of_mass(scribble, labeled_array,
|
||||
range(1, num_features + 1))
|
||||
point_coords = np.array(centers)
|
||||
point_labels = np.array([1] * len(centers))
|
||||
sample = {'point_coords': point_coords, 'point_labels': point_labels}
|
||||
sample = {
|
||||
'point_coords': point_coords,
|
||||
'point_labels': point_labels
|
||||
}
|
||||
|
||||
elif task_type == 'mask_box':
|
||||
scribble = mask.transpose(2, 1, 0)[0]
|
||||
labeled_array, num_features = ndimage.label(scribble >= 255)
|
||||
centers = ndimage.center_of_mass(scribble, labeled_array, range(1, num_features + 1))
|
||||
centers = ndimage.center_of_mass(scribble, labeled_array,
|
||||
range(1, num_features + 1))
|
||||
centers = np.array(centers)
|
||||
### (x1, y1, x2, y2)
|
||||
# (x1, y1, x2, y2)
|
||||
x_min = centers[:, 0].min()
|
||||
x_max = centers[:, 0].max()
|
||||
y_min = centers[:, 1].min()
|
||||
@@ -365,12 +366,13 @@ class SAMAnnotatorDraw(BaseAnnotator, metaclass=ABCMeta):
|
||||
sample = {'box': input_box}
|
||||
|
||||
self.sam_predictor.set_image(image)
|
||||
masks, scores, logits = self.sam_predictor.predict(**sample, multimask_output=True)
|
||||
masks, scores, logits = self.sam_predictor.predict(
|
||||
**sample, multimask_output=True)
|
||||
index = np.argmax(scores)
|
||||
|
||||
ret_data = {
|
||||
"mask": (masks[index]* 255).astype(np.uint8),
|
||||
"score": scores[index]
|
||||
'mask': (masks[index] * 255).astype(np.uint8),
|
||||
'score': scores[index]
|
||||
}
|
||||
return ret_data
|
||||
|
||||
@@ -379,4 +381,4 @@ class SAMAnnotatorDraw(BaseAnnotator, metaclass=ABCMeta):
|
||||
return dict_to_yaml('ANNOTATORS',
|
||||
__class__.__name__,
|
||||
SAMAnnotatorDraw.para_dict,
|
||||
set_name=True)
|
||||
set_name=True)
|
||||
|
||||
@@ -1,14 +1,11 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
|
||||
import math
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from abc import ABCMeta
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
import torchvision.transforms as TT
|
||||
from einops import rearrange
|
||||
from scepter.modules.annotator.base_annotator import BaseAnnotator
|
||||
from scepter.modules.annotator.registry import ANNOTATORS
|
||||
|
||||
@@ -7,5 +7,6 @@ from scepter.modules.data.dataset.dataset import (Image2ImageDataset,
|
||||
ImageTextPairDataset,
|
||||
Text2ImageDataset)
|
||||
from scepter.modules.data.dataset.ms_dataset import (
|
||||
ImageTextPairFolderDataset, ImageTextPairMSDataset)
|
||||
ImageTextPairFolderDataset, ImageTextPairMSDataset,
|
||||
ImageTextPairMSDatasetForACE)
|
||||
from scepter.modules.data.dataset.registry import DATASETS
|
||||
|
||||
@@ -1,16 +1,28 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
|
||||
import io
|
||||
import math
|
||||
import numbers
|
||||
import os
|
||||
import sys
|
||||
from collections import defaultdict
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchvision.transforms as T
|
||||
from PIL import Image
|
||||
from torchvision.transforms.functional import InterpolationMode
|
||||
|
||||
from scepter.modules.data.dataset.base_dataset import BaseDataset
|
||||
from scepter.modules.data.dataset.registry import DATASETS
|
||||
from scepter.modules.transform.io import pillow_convert
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
|
||||
Image.MAX_IMAGE_PIXELS = None
|
||||
|
||||
|
||||
@DATASETS.register_class()
|
||||
class ImageTextPairMSDataset(BaseDataset):
|
||||
@@ -102,7 +114,7 @@ class ImageTextPairMSDataset(BaseDataset):
|
||||
self.output_size = [self.output_size, self.output_size]
|
||||
# Use modelscope dataset
|
||||
if not ms_dataset_name:
|
||||
raise (
|
||||
raise ValueError(
|
||||
'Your must set MS_DATASET_NAME as modelscope dataset or your local dataset orignized '
|
||||
'as modelscope dataset.')
|
||||
if FS.exists(ms_dataset_name):
|
||||
@@ -125,7 +137,7 @@ class ImageTextPairMSDataset(BaseDataset):
|
||||
split=ms_dataset_split,
|
||||
download_mode=DownloadMode.FORCE_REDOWNLOAD)
|
||||
except Exception as sec_e:
|
||||
raise f'Load Modelscope dataset failed {sec_e}.'
|
||||
raise ValueError(f'Load Modelscope dataset failed {sec_e}.')
|
||||
if ms_remap_keys:
|
||||
self.data = self.data.remap_columns(ms_remap_keys.get_dict())
|
||||
|
||||
@@ -245,7 +257,7 @@ class ImageTextPairFolderDataset(BaseDataset):
|
||||
self.output_size = [self.output_size, self.output_size]
|
||||
# Use modelscope dataset
|
||||
if not data_folder or not FS.exists(data_folder):
|
||||
raise ('Your must set datafolder for local dataset.')
|
||||
raise ValueError('Your must set datafolder for local dataset.')
|
||||
data_folder = FS.get_dir_to_local_dir(data_folder)
|
||||
all_lines = open(os.path.join(data_folder, 'train.csv'),
|
||||
'r').read().split('\n')
|
||||
@@ -311,3 +323,247 @@ class ImageTextPairFolderDataset(BaseDataset):
|
||||
__class__.__name__,
|
||||
ImageTextPairMSDataset.para_dict,
|
||||
set_name=True)
|
||||
|
||||
|
||||
@DATASETS.register_class()
|
||||
class ImageTextPairMSDatasetForACE(BaseDataset):
|
||||
para_dict = {
|
||||
'MS_DATASET_NAME': {
|
||||
'value': '',
|
||||
'description': 'Modelscope dataset name.'
|
||||
},
|
||||
'MS_DATASET_NAMESPACE': {
|
||||
'value': '',
|
||||
'description': 'Modelscope dataset namespace.'
|
||||
},
|
||||
'MS_DATASET_SUBNAME': {
|
||||
'value': '',
|
||||
'description': 'Modelscope dataset subname.'
|
||||
},
|
||||
'MS_DATASET_SPLIT': {
|
||||
'value': '',
|
||||
'description':
|
||||
'Modelscope dataset split set name, default is train.'
|
||||
},
|
||||
'MS_REMAP_KEYS': {
|
||||
'value':
|
||||
None,
|
||||
'description':
|
||||
'Modelscope dataset header of list file, the default is Target:FILE; '
|
||||
'If your file is not this header, please set this field, which is a map dict.'
|
||||
"For example, { 'Image:FILE': 'Target:FILE' } will replace the filed Image:FILE to Target:FILE"
|
||||
},
|
||||
'MS_REMAP_PATH': {
|
||||
'value':
|
||||
None,
|
||||
'description':
|
||||
'When modelscope dataset name is not None, that means you use the dataset from modelscope,'
|
||||
' default is None. But if you want to use the datalist from modelscope and the file from '
|
||||
'local device, you can use this field to set the root path of your images. '
|
||||
},
|
||||
'TRIGGER_WORDS': {
|
||||
'value':
|
||||
'',
|
||||
'description':
|
||||
'The words used to describe the common features of your data, especially when you customize a '
|
||||
'tuner. Use these words you can get what you want.'
|
||||
},
|
||||
'REPLACE_STYLE': {
|
||||
'value':
|
||||
False,
|
||||
'description':
|
||||
'Whether use the MS_DATASET_SUBNAME to replace the word in your description, default is False.'
|
||||
},
|
||||
'HIGHLIGHT_KEYWORDS': {
|
||||
'value':
|
||||
'',
|
||||
'description':
|
||||
'The keywords you want to highlight in prompt, which will be replace by <HIGHLIGHT_KEYWORDS>.'
|
||||
},
|
||||
'KEYWORDS_SIGN': {
|
||||
'value':
|
||||
'',
|
||||
'description':
|
||||
'The keywords sign you want to add, which is like <{HIGHLIGHT_KEYWORDS}{KEYWORDS_SIGN}>'
|
||||
},
|
||||
'OUTPUT_SIZE': {
|
||||
'value':
|
||||
None,
|
||||
'description':
|
||||
'If you use the FlexibleResize transforms, this filed will output the image_size as [h, w],'
|
||||
'which will be used to set the output size of images used to train the model.'
|
||||
},
|
||||
}
|
||||
|
||||
def __init__(self, cfg, logger=None):
|
||||
super().__init__(cfg=cfg, logger=logger)
|
||||
from modelscope import MsDataset
|
||||
from modelscope.utils.constant import DownloadMode
|
||||
ms_dataset_name = cfg.get('MS_DATASET_NAME', None)
|
||||
ms_dataset_namespace = cfg.get('MS_DATASET_NAMESPACE', None)
|
||||
ms_dataset_subname = cfg.get('MS_DATASET_SUBNAME', None)
|
||||
ms_dataset_split = cfg.get('MS_DATASET_SPLIT', 'train')
|
||||
ms_remap_keys = cfg.get('MS_REMAP_KEYS', None)
|
||||
ms_remap_path = cfg.get('MS_REMAP_PATH', None)
|
||||
|
||||
self.max_seq_len = cfg.get('MAX_SEQ_LEN', 1024)
|
||||
self.max_aspect_ratio = cfg.get('MAX_ASPECT_RATIO', 4)
|
||||
self.d = cfg.get('DOWNSAMPLE_RATIO', 16)
|
||||
self.replace_style = cfg.get('REPLACE_STYLE', False)
|
||||
self.trigger_words = cfg.get('TRIGGER_WORDS', '')
|
||||
self.replace_keywords = cfg.get('HIGHLIGHT_KEYWORDS', '')
|
||||
self.keywords_sign = cfg.get('KEYWORDS_SIGN', '')
|
||||
self.add_indicator = cfg.get('ADD_INDICATOR', False)
|
||||
# Use modelscope dataset
|
||||
if not ms_dataset_name:
|
||||
raise ValueError(
|
||||
'Your must set MS_DATASET_NAME as modelscope dataset or your local dataset orignized '
|
||||
'as modelscope dataset.')
|
||||
if FS.exists(ms_dataset_name):
|
||||
ms_dataset_name = FS.get_dir_to_local_dir(ms_dataset_name)
|
||||
self.ms_dataset_name = ms_dataset_name
|
||||
# ms_remap_path = ms_dataset_name
|
||||
try:
|
||||
self.data = MsDataset.load(str(ms_dataset_name),
|
||||
namespace=ms_dataset_namespace,
|
||||
subset_name=ms_dataset_subname,
|
||||
split=ms_dataset_split)
|
||||
except Exception:
|
||||
self.logger.info(
|
||||
"Load Modelscope dataset failed, retry with download_mode='force_redownload'."
|
||||
)
|
||||
try:
|
||||
self.data = MsDataset.load(
|
||||
str(ms_dataset_name),
|
||||
namespace=ms_dataset_namespace,
|
||||
subset_name=ms_dataset_subname,
|
||||
split=ms_dataset_split,
|
||||
download_mode=DownloadMode.FORCE_REDOWNLOAD)
|
||||
except Exception as sec_e:
|
||||
raise ValueError(f'Load Modelscope dataset failed {sec_e}.')
|
||||
if ms_remap_keys:
|
||||
self.data = self.data.remap_columns(ms_remap_keys.get_dict())
|
||||
|
||||
if ms_remap_path:
|
||||
|
||||
def map_func(example):
|
||||
return {
|
||||
k: os.path.join(ms_remap_path, v)
|
||||
if k.endswith(':FILE') else v
|
||||
for k, v in example.items()
|
||||
}
|
||||
|
||||
self.data = self.data.ds_instance.map(map_func)
|
||||
|
||||
self.transforms = T.Compose([
|
||||
T.ToTensor(),
|
||||
T.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
|
||||
])
|
||||
|
||||
def __len__(self):
|
||||
if self.mode == 'train':
|
||||
return sys.maxsize
|
||||
else:
|
||||
return len(self.data)
|
||||
|
||||
def _get(self, index: int):
|
||||
current_data = self.data[index % len(self.data)]
|
||||
|
||||
tar_image_path = current_data.get('Target:FILE', '')
|
||||
src_image_path = current_data.get('Source:FILE', '')
|
||||
|
||||
style = current_data.get('Style', '')
|
||||
prompt = current_data.get('Prompt', current_data.get('prompt', ''))
|
||||
if self.replace_style and not style == '':
|
||||
prompt = prompt.replace(style, f'<{self.keywords_sign}>')
|
||||
|
||||
elif not self.replace_keywords.strip() == '':
|
||||
prompt = prompt.replace(
|
||||
self.replace_keywords,
|
||||
'<' + self.replace_keywords + f'{self.keywords_sign}>')
|
||||
|
||||
if not self.trigger_words == '':
|
||||
prompt = self.trigger_words.strip() + ' ' + prompt
|
||||
|
||||
src_image = self.load_image(self.ms_dataset_name,
|
||||
src_image_path,
|
||||
cvt_type='RGB')
|
||||
tar_image = self.load_image(self.ms_dataset_name,
|
||||
tar_image_path,
|
||||
cvt_type='RGB')
|
||||
src_image = self.image_preprocess(src_image)
|
||||
tar_image = self.image_preprocess(tar_image)
|
||||
|
||||
tar_image = self.transforms(tar_image)
|
||||
src_image = self.transforms(src_image)
|
||||
src_mask = torch.ones_like(src_image[[0]])
|
||||
tar_mask = torch.ones_like(tar_image[[0]])
|
||||
if self.add_indicator:
|
||||
if '{image}' not in prompt:
|
||||
prompt = '{image}, ' + prompt
|
||||
|
||||
return {
|
||||
'edit_image': [src_image],
|
||||
'edit_image_mask': [src_mask],
|
||||
'image': tar_image,
|
||||
'image_mask': tar_mask,
|
||||
'prompt': [prompt],
|
||||
}
|
||||
|
||||
def load_image(self, prefix, img_path, cvt_type=None):
|
||||
if img_path is None or img_path == '':
|
||||
return None
|
||||
img_path = os.path.join(prefix, img_path)
|
||||
with FS.get_object(img_path) as image_bytes:
|
||||
image = Image.open(io.BytesIO(image_bytes))
|
||||
if cvt_type is not None:
|
||||
image = pillow_convert(image, cvt_type)
|
||||
return image
|
||||
|
||||
def image_preprocess(self,
|
||||
img,
|
||||
size=None,
|
||||
interpolation=InterpolationMode.BILINEAR):
|
||||
H, W = img.height, img.width
|
||||
if H / W > self.max_aspect_ratio:
|
||||
img = T.CenterCrop((self.max_aspect_ratio * W, W))(img)
|
||||
elif W / H > self.max_aspect_ratio:
|
||||
img = T.CenterCrop((H, self.max_aspect_ratio * H))(img)
|
||||
|
||||
if size is None:
|
||||
# resize image for max_seq_len, while keep the aspect ratio
|
||||
H, W = img.height, img.width
|
||||
scale = min(
|
||||
1.0,
|
||||
math.sqrt(self.max_seq_len / ((H / self.d) * (W / self.d))))
|
||||
rH = int(
|
||||
H * scale) // self.d * self.d # ensure divisible by self.d
|
||||
rW = int(W * scale) // self.d * self.d
|
||||
else:
|
||||
rH, rW = size
|
||||
img = T.Resize((rH, rW), interpolation=interpolation,
|
||||
antialias=True)(img)
|
||||
return np.array(img, dtype=np.uint8)
|
||||
|
||||
@staticmethod
|
||||
def get_config_template():
|
||||
return dict_to_yaml('DATASet',
|
||||
__class__.__name__,
|
||||
ImageTextPairMSDatasetForACE.para_dict,
|
||||
set_name=True)
|
||||
|
||||
@staticmethod
|
||||
def collate_fn(batch):
|
||||
collect = defaultdict(list)
|
||||
for sample in batch:
|
||||
for k, v in sample.items():
|
||||
collect[k].append(v)
|
||||
|
||||
new_batch = dict()
|
||||
for k, v in collect.items():
|
||||
if all([i is None for i in v]):
|
||||
new_batch[k] = None
|
||||
else:
|
||||
new_batch[k] = v
|
||||
|
||||
return new_batch
|
||||
|
||||
@@ -0,0 +1,376 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import copy
|
||||
import math
|
||||
import random
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
import torchvision.transforms.functional as TF
|
||||
from PIL import Image
|
||||
|
||||
from scepter.modules.model.registry import DIFFUSIONS
|
||||
from scepter.modules.model.utils.basic_utils import check_list_of_list
|
||||
from scepter.modules.model.utils.basic_utils import \
|
||||
pack_imagelist_into_tensor_v2 as pack_imagelist_into_tensor
|
||||
from scepter.modules.model.utils.basic_utils import (
|
||||
to_device, unpack_tensor_into_imagelist)
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.logger import get_logger
|
||||
|
||||
from .diffusion_inference import DiffusionInference, get_model
|
||||
|
||||
|
||||
def process_edit_image(images,
|
||||
masks,
|
||||
tasks,
|
||||
max_seq_len=1024,
|
||||
max_aspect_ratio=4,
|
||||
d=16,
|
||||
**kwargs):
|
||||
|
||||
if not isinstance(images, list):
|
||||
images = [images]
|
||||
if not isinstance(masks, list):
|
||||
masks = [masks]
|
||||
if not isinstance(tasks, list):
|
||||
tasks = [tasks]
|
||||
|
||||
img_tensors = []
|
||||
mask_tensors = []
|
||||
for img, mask, task in zip(images, masks, tasks):
|
||||
if mask is None or mask == '':
|
||||
mask = Image.new('L', img.size, 0)
|
||||
W, H = img.size
|
||||
if H / W > max_aspect_ratio:
|
||||
img = TF.center_crop(img, [int(max_aspect_ratio * W), W])
|
||||
mask = TF.center_crop(mask, [int(max_aspect_ratio * W), W])
|
||||
elif W / H > max_aspect_ratio:
|
||||
img = TF.center_crop(img, [H, int(max_aspect_ratio * H)])
|
||||
mask = TF.center_crop(mask, [H, int(max_aspect_ratio * H)])
|
||||
|
||||
H, W = img.height, img.width
|
||||
scale = min(1.0, math.sqrt(max_seq_len / ((H / d) * (W / d))))
|
||||
rH = int(H * scale) // d * d # ensure divisible by self.d
|
||||
rW = int(W * scale) // d * d
|
||||
|
||||
img = TF.resize(img, (rH, rW),
|
||||
interpolation=TF.InterpolationMode.BICUBIC)
|
||||
mask = TF.resize(mask, (rH, rW),
|
||||
interpolation=TF.InterpolationMode.NEAREST_EXACT)
|
||||
|
||||
mask = np.asarray(mask)
|
||||
mask = np.where(mask > 128, 1, 0)
|
||||
mask = mask.astype(
|
||||
np.float32) if np.any(mask) else np.ones_like(mask).astype(
|
||||
np.float32)
|
||||
|
||||
img_tensor = TF.to_tensor(img).to(we.device_id)
|
||||
img_tensor = TF.normalize(img_tensor,
|
||||
mean=[0.5, 0.5, 0.5],
|
||||
std=[0.5, 0.5, 0.5])
|
||||
mask_tensor = TF.to_tensor(mask).to(we.device_id)
|
||||
if task in ['inpainting', 'Try On', 'Inpainting']:
|
||||
mask_indicator = mask_tensor.repeat(3, 1, 1)
|
||||
img_tensor[mask_indicator == 1] = -1.0
|
||||
img_tensors.append(img_tensor)
|
||||
mask_tensors.append(mask_tensor)
|
||||
return img_tensors, mask_tensors
|
||||
|
||||
|
||||
class TextEmbedding(nn.Module):
|
||||
def __init__(self, embedding_shape):
|
||||
super().__init__()
|
||||
self.pos = nn.Parameter(data=torch.zeros(embedding_shape))
|
||||
|
||||
|
||||
class ACEInference(DiffusionInference):
|
||||
def __init__(self, logger=None):
|
||||
if logger is None:
|
||||
logger = get_logger(name='scepter')
|
||||
self.logger = logger
|
||||
self.loaded_model = {}
|
||||
self.loaded_model_name = [
|
||||
'diffusion_model', 'first_stage_model', 'cond_stage_model'
|
||||
]
|
||||
|
||||
def init_from_cfg(self, cfg):
|
||||
self.name = cfg.NAME
|
||||
self.is_default = cfg.get('IS_DEFAULT', False)
|
||||
module_paras = self.load_default(cfg.get('DEFAULT_PARAS', None))
|
||||
assert cfg.have('MODEL')
|
||||
|
||||
self.diffusion_model = self.infer_model(
|
||||
cfg.MODEL.DIFFUSION_MODEL, module_paras.get(
|
||||
'DIFFUSION_MODEL',
|
||||
None)) if cfg.MODEL.have('DIFFUSION_MODEL') else None
|
||||
self.first_stage_model = self.infer_model(
|
||||
cfg.MODEL.FIRST_STAGE_MODEL,
|
||||
module_paras.get(
|
||||
'FIRST_STAGE_MODEL',
|
||||
None)) if cfg.MODEL.have('FIRST_STAGE_MODEL') else None
|
||||
self.cond_stage_model = self.infer_model(
|
||||
cfg.MODEL.COND_STAGE_MODEL,
|
||||
module_paras.get(
|
||||
'COND_STAGE_MODEL',
|
||||
None)) if cfg.MODEL.have('COND_STAGE_MODEL') else None
|
||||
self.diffusion = DIFFUSIONS.build(cfg.MODEL.DIFFUSION,
|
||||
logger=self.logger)
|
||||
|
||||
self.interpolate_func = lambda x: (F.interpolate(
|
||||
x.unsqueeze(0),
|
||||
scale_factor=1 / self.size_factor,
|
||||
mode='nearest-exact') if x is not None else None)
|
||||
self.text_indentifers = cfg.MODEL.get('TEXT_IDENTIFIER', [])
|
||||
self.use_text_pos_embeddings = cfg.MODEL.get('USE_TEXT_POS_EMBEDDINGS',
|
||||
False)
|
||||
if self.use_text_pos_embeddings:
|
||||
self.text_position_embeddings = TextEmbedding(
|
||||
(10, 4096)).eval().requires_grad_(False).to(we.device_id)
|
||||
else:
|
||||
self.text_position_embeddings = None
|
||||
|
||||
self.max_seq_len = cfg.MODEL.DIFFUSION_MODEL.MAX_SEQ_LEN
|
||||
self.scale_factor = cfg.get('SCALE_FACTOR', 0.18215)
|
||||
self.size_factor = cfg.get('SIZE_FACTOR', 8)
|
||||
self.decoder_bias = cfg.get('DECODER_BIAS', 0)
|
||||
self.default_n_prompt = cfg.get('DEFAULT_N_PROMPT', '')
|
||||
|
||||
@torch.no_grad()
|
||||
def encode_first_stage(self, x, **kwargs):
|
||||
_, dtype = self.get_function_info(self.first_stage_model, 'encode')
|
||||
with torch.autocast('cuda',
|
||||
enabled=(dtype != 'float32'),
|
||||
dtype=getattr(torch, dtype)):
|
||||
z = [
|
||||
self.scale_factor * get_model(self.first_stage_model)._encode(
|
||||
i.unsqueeze(0).to(getattr(torch, dtype))) for i in x
|
||||
]
|
||||
return z
|
||||
|
||||
@torch.no_grad()
|
||||
def decode_first_stage(self, z):
|
||||
_, dtype = self.get_function_info(self.first_stage_model, 'decode')
|
||||
with torch.autocast('cuda',
|
||||
enabled=(dtype != 'float32'),
|
||||
dtype=getattr(torch, dtype)):
|
||||
x = [
|
||||
get_model(self.first_stage_model)._decode(
|
||||
1. / self.scale_factor * i.to(getattr(torch, dtype)))
|
||||
for i in z
|
||||
]
|
||||
return x
|
||||
|
||||
@torch.no_grad()
|
||||
def __call__(self,
|
||||
image=None,
|
||||
mask=None,
|
||||
prompt='',
|
||||
task=None,
|
||||
negative_prompt='',
|
||||
output_height=512,
|
||||
output_width=512,
|
||||
sampler='ddim',
|
||||
sample_steps=20,
|
||||
guide_scale=4.5,
|
||||
guide_rescale=0.5,
|
||||
seed=-1,
|
||||
history_io=None,
|
||||
tar_index=0,
|
||||
**kwargs):
|
||||
input_image, input_mask = image, mask
|
||||
g = torch.Generator(device=we.device_id)
|
||||
seed = seed if seed >= 0 else random.randint(0, 2**32 - 1)
|
||||
g.manual_seed(int(seed))
|
||||
|
||||
if input_image is not None:
|
||||
# assert isinstance(input_image, list) and isinstance(input_mask, list)
|
||||
if task is None:
|
||||
task = [''] * len(input_image)
|
||||
if not isinstance(prompt, list):
|
||||
prompt = [prompt] * len(input_image)
|
||||
if history_io is not None and len(history_io) > 0:
|
||||
his_image, his_maks, his_prompt, his_task = history_io[
|
||||
'image'], history_io['mask'], history_io[
|
||||
'prompt'], history_io['task']
|
||||
assert len(his_image) == len(his_maks) == len(
|
||||
his_prompt) == len(his_task)
|
||||
input_image = his_image + input_image
|
||||
input_mask = his_maks + input_mask
|
||||
task = his_task + task
|
||||
prompt = his_prompt + [prompt[-1]]
|
||||
prompt = [
|
||||
pp.replace('{image}', f'{{image{i}}}') if i > 0 else pp
|
||||
for i, pp in enumerate(prompt)
|
||||
]
|
||||
|
||||
edit_image, edit_image_mask = process_edit_image(
|
||||
input_image, input_mask, task, max_seq_len=self.max_seq_len)
|
||||
|
||||
image, image_mask = edit_image[tar_index], edit_image_mask[
|
||||
tar_index]
|
||||
edit_image, edit_image_mask = [edit_image], [edit_image_mask]
|
||||
|
||||
else:
|
||||
edit_image = edit_image_mask = [[]]
|
||||
image = torch.zeros(
|
||||
size=[3, int(output_height),
|
||||
int(output_width)])
|
||||
image_mask = torch.ones(
|
||||
size=[1, int(output_height),
|
||||
int(output_width)])
|
||||
if not isinstance(prompt, list):
|
||||
prompt = [prompt]
|
||||
|
||||
image, image_mask, prompt = [image], [image_mask], [prompt]
|
||||
assert check_list_of_list(prompt) and check_list_of_list(
|
||||
edit_image) and check_list_of_list(edit_image_mask)
|
||||
# Assign Negative Prompt
|
||||
if isinstance(negative_prompt, list):
|
||||
negative_prompt = negative_prompt[0]
|
||||
assert isinstance(negative_prompt, str)
|
||||
|
||||
n_prompt = copy.deepcopy(prompt)
|
||||
for nn_p_id, nn_p in enumerate(n_prompt):
|
||||
assert isinstance(nn_p, list)
|
||||
n_prompt[nn_p_id][-1] = negative_prompt
|
||||
|
||||
ctx, null_ctx = {}, {}
|
||||
|
||||
# Get Noise Shape
|
||||
self.dynamic_load(self.first_stage_model, 'first_stage_model')
|
||||
image = to_device(image)
|
||||
x = self.encode_first_stage(image)
|
||||
self.dynamic_unload(self.first_stage_model,
|
||||
'first_stage_model',
|
||||
skip_loaded=True)
|
||||
noise = [
|
||||
torch.empty(*i.shape, device=we.device_id).normal_(generator=g)
|
||||
for i in x
|
||||
]
|
||||
noise, x_shapes = pack_imagelist_into_tensor(noise)
|
||||
ctx['x_shapes'] = null_ctx['x_shapes'] = x_shapes
|
||||
|
||||
image_mask = to_device(image_mask, strict=False)
|
||||
cond_mask = [self.interpolate_func(i) for i in image_mask
|
||||
] if image_mask is not None else [None] * len(image)
|
||||
ctx['x_mask'] = null_ctx['x_mask'] = cond_mask
|
||||
|
||||
# Encode Prompt
|
||||
self.dynamic_load(self.cond_stage_model, 'cond_stage_model')
|
||||
function_name, dtype = self.get_function_info(self.cond_stage_model)
|
||||
cont, cont_mask = getattr(get_model(self.cond_stage_model),
|
||||
function_name)(prompt)
|
||||
cont, cont_mask = self.cond_stage_embeddings(prompt, edit_image, cont,
|
||||
cont_mask)
|
||||
null_cont, null_cont_mask = getattr(get_model(self.cond_stage_model),
|
||||
function_name)(n_prompt)
|
||||
null_cont, null_cont_mask = self.cond_stage_embeddings(
|
||||
prompt, edit_image, null_cont, null_cont_mask)
|
||||
self.dynamic_unload(self.cond_stage_model,
|
||||
'cond_stage_model',
|
||||
skip_loaded=False)
|
||||
ctx['crossattn'] = cont
|
||||
null_ctx['crossattn'] = null_cont
|
||||
|
||||
# Encode Edit Images
|
||||
self.dynamic_load(self.first_stage_model, 'first_stage_model')
|
||||
edit_image = [to_device(i, strict=False) for i in edit_image]
|
||||
edit_image_mask = [to_device(i, strict=False) for i in edit_image_mask]
|
||||
e_img, e_mask = [], []
|
||||
for u, m in zip(edit_image, edit_image_mask):
|
||||
if u is None:
|
||||
continue
|
||||
if m is None:
|
||||
m = [None] * len(u)
|
||||
e_img.append(self.encode_first_stage(u, **kwargs))
|
||||
e_mask.append([self.interpolate_func(i) for i in m])
|
||||
self.dynamic_unload(self.first_stage_model,
|
||||
'first_stage_model',
|
||||
skip_loaded=True)
|
||||
null_ctx['edit'] = ctx['edit'] = e_img
|
||||
null_ctx['edit_mask'] = ctx['edit_mask'] = e_mask
|
||||
|
||||
# Diffusion Process
|
||||
self.dynamic_load(self.diffusion_model, 'diffusion_model')
|
||||
function_name, dtype = self.get_function_info(self.diffusion_model)
|
||||
with torch.autocast('cuda',
|
||||
enabled=dtype in ('float16', 'bfloat16'),
|
||||
dtype=getattr(torch, dtype)):
|
||||
latent = self.diffusion.sample(
|
||||
noise=noise,
|
||||
sampler=sampler,
|
||||
model=get_model(self.diffusion_model),
|
||||
model_kwargs=[{
|
||||
'cond':
|
||||
ctx,
|
||||
'mask':
|
||||
cont_mask,
|
||||
'text_position_embeddings':
|
||||
self.text_position_embeddings.pos if hasattr(
|
||||
self.text_position_embeddings, 'pos') else None
|
||||
}, {
|
||||
'cond':
|
||||
null_ctx,
|
||||
'mask':
|
||||
null_cont_mask,
|
||||
'text_position_embeddings':
|
||||
self.text_position_embeddings.pos if hasattr(
|
||||
self.text_position_embeddings, 'pos') else None
|
||||
}] if guide_scale is not None and guide_scale > 1 else {
|
||||
'cond':
|
||||
null_ctx,
|
||||
'mask':
|
||||
cont_mask,
|
||||
'text_position_embeddings':
|
||||
self.text_position_embeddings.pos if hasattr(
|
||||
self.text_position_embeddings, 'pos') else None
|
||||
},
|
||||
steps=sample_steps,
|
||||
show_progress=True,
|
||||
seed=seed,
|
||||
guide_scale=guide_scale,
|
||||
guide_rescale=guide_rescale,
|
||||
return_intermediate=None,
|
||||
**kwargs)
|
||||
self.dynamic_unload(self.diffusion_model,
|
||||
'diffusion_model',
|
||||
skip_loaded=False)
|
||||
|
||||
# Decode to Pixel Space
|
||||
self.dynamic_load(self.first_stage_model, 'first_stage_model')
|
||||
samples = unpack_tensor_into_imagelist(latent, x_shapes)
|
||||
x_samples = self.decode_first_stage(samples)
|
||||
self.dynamic_unload(self.first_stage_model,
|
||||
'first_stage_model',
|
||||
skip_loaded=False)
|
||||
|
||||
imgs = [
|
||||
torch.clamp((x_i + 1.0) / 2.0 + self.decoder_bias / 255,
|
||||
min=0.0,
|
||||
max=1.0).squeeze(0).permute(1, 2, 0).cpu().numpy()
|
||||
for x_i in x_samples
|
||||
]
|
||||
imgs = [Image.fromarray((img * 255).astype(np.uint8)) for img in imgs]
|
||||
return imgs
|
||||
|
||||
def cond_stage_embeddings(self, prompt, edit_image, cont, cont_mask):
|
||||
if self.use_text_pos_embeddings and not torch.sum(
|
||||
self.text_position_embeddings.pos) > 0:
|
||||
identifier_cont, _ = getattr(get_model(self.cond_stage_model),
|
||||
'encode')(self.text_indentifers,
|
||||
return_mask=True)
|
||||
self.text_position_embeddings.load_state_dict(
|
||||
{'pos': identifier_cont[:, 0, :]})
|
||||
|
||||
cont_, cont_mask_ = [], []
|
||||
for pp, edit, c, cm in zip(prompt, edit_image, cont, cont_mask):
|
||||
if isinstance(pp, list):
|
||||
cont_.append([c[-1], *c] if len(edit) > 0 else [c[-1]])
|
||||
cont_mask_.append([cm[-1], *cm] if len(edit) > 0 else [cm[-1]])
|
||||
else:
|
||||
raise NotImplementedError
|
||||
|
||||
return cont_, cont_mask_
|
||||
@@ -11,7 +11,7 @@ from PIL.Image import Image
|
||||
from scepter.modules.model.network.diffusion.diffusion import GaussianDiffusion
|
||||
from scepter.modules.model.network.diffusion.schedules import noise_schedule
|
||||
from scepter.modules.model.registry import (BACKBONES, EMBEDDERS, MODELS,
|
||||
TOKENIZERS)
|
||||
TOKENIZERS, DIFFUSIONS)
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
from scepter.studio.utils.env import get_available_memory
|
||||
@@ -49,7 +49,10 @@ class DiffusionInference():
|
||||
assert cfg.have('MODEL')
|
||||
if self.is_redefine_paras:
|
||||
cfg.MODEL = self.redefine_paras(cfg.MODEL)
|
||||
self.diffusion = self.load_schedule(cfg.MODEL.SCHEDULE)
|
||||
if 'DIFFUSION' in cfg.MODEL:
|
||||
self.diffusion = DIFFUSIONS.build(cfg.MODEL.DIFFUSION, logger=self.logger)
|
||||
else:
|
||||
self.diffusion = self.load_schedule(cfg.MODEL.SCHEDULE)
|
||||
self.diffusion_model = self.infer_model(
|
||||
cfg.MODEL.DIFFUSION_MODEL, module_paras.get(
|
||||
'DIFFUSION_MODEL',
|
||||
|
||||
@@ -1,20 +1,12 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import copy
|
||||
import os.path
|
||||
import random
|
||||
from collections import OrderedDict
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from PIL.Image import Image
|
||||
|
||||
from scepter.modules.model.network.diffusion.diffusion import GaussianDiffusion
|
||||
from scepter.modules.model.network.diffusion.schedules import noise_schedule
|
||||
from scepter.modules.model.registry import (BACKBONES, EMBEDDERS, MODELS,
|
||||
TOKENIZERS)
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
from scepter.studio.utils.env import get_available_memory
|
||||
|
||||
from .control_inference import ControlInference
|
||||
from .diffusion_inference import DiffusionInference, get_model
|
||||
|
||||
@@ -3,10 +3,8 @@
|
||||
import copy
|
||||
import random
|
||||
|
||||
import gradio as gr
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
import torchvision.transforms.functional as TF
|
||||
|
||||
from scepter.modules.model.network.diffusion.diffusion import \
|
||||
GaussianDiffusionRF
|
||||
from scepter.modules.utils.distribute import we
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from scepter.modules.model.backbone import (autoencoder, image, mmdit, pixart,
|
||||
unet, utils, video, flux)
|
||||
from scepter.modules.model.backbone import (ace, autoencoder, flux, image,
|
||||
mmdit, pixart, unet, utils, video)
|
||||
|
||||
@@ -0,0 +1,3 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from .ace import ACE
|
||||
@@ -0,0 +1,372 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import re
|
||||
from collections import OrderedDict
|
||||
from functools import partial
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from einops import rearrange
|
||||
from torch.nn.utils.rnn import pad_sequence
|
||||
from torch.utils.checkpoint import checkpoint_sequential
|
||||
|
||||
from scepter.modules.model.backbone.transformer.layers import (Mlp,
|
||||
T2IFinalLayer,
|
||||
TimestepEmbedder
|
||||
)
|
||||
from scepter.modules.model.backbone.transformer.patchify import PatchEmbed
|
||||
from scepter.modules.model.backbone.transformer.pos_embed import rope_params
|
||||
from scepter.modules.model.base_model import BaseModel
|
||||
from scepter.modules.model.registry import BACKBONES
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.utils.file_system import FS
|
||||
|
||||
from .layers import ACEBlock
|
||||
|
||||
|
||||
@BACKBONES.register_class()
|
||||
class ACE(BaseModel):
|
||||
|
||||
para_dict = {
|
||||
'PATCH_SIZE': {
|
||||
'value': 2,
|
||||
'description': ''
|
||||
},
|
||||
'IN_CHANNELS': {
|
||||
'value': 4,
|
||||
'description': ''
|
||||
},
|
||||
'HIDDEN_SIZE': {
|
||||
'value': 1152,
|
||||
'description': ''
|
||||
},
|
||||
'DEPTH': {
|
||||
'value': 28,
|
||||
'description': ''
|
||||
},
|
||||
'NUM_HEADS': {
|
||||
'value': 16,
|
||||
'description': ''
|
||||
},
|
||||
'MLP_RATIO': {
|
||||
'value': 4.0,
|
||||
'description': ''
|
||||
},
|
||||
'PRED_SIGMA': {
|
||||
'value': True,
|
||||
'description': ''
|
||||
},
|
||||
'DROP_PATH': {
|
||||
'value': 0.,
|
||||
'description': ''
|
||||
},
|
||||
'WINDOW_SIZE': {
|
||||
'value': 0,
|
||||
'description': ''
|
||||
},
|
||||
'WINDOW_BLOCK_INDEXES': {
|
||||
'value': None,
|
||||
'description': ''
|
||||
},
|
||||
'Y_CHANNELS': {
|
||||
'value': 4096,
|
||||
'description': ''
|
||||
},
|
||||
'ATTENTION_BACKEND': {
|
||||
'value': None,
|
||||
'description': ''
|
||||
},
|
||||
'QK_NORM': {
|
||||
'value': True,
|
||||
'description': 'Whether to use RMSNorm for query and key.',
|
||||
},
|
||||
}
|
||||
para_dict.update(BaseModel.para_dict)
|
||||
|
||||
def __init__(self, cfg, logger):
|
||||
super().__init__(cfg, logger=logger)
|
||||
self.window_block_indexes = cfg.get('WINDOW_BLOCK_INDEXES', None)
|
||||
if self.window_block_indexes is None:
|
||||
self.window_block_indexes = []
|
||||
self.pred_sigma = cfg.get('PRED_SIGMA', True)
|
||||
self.in_channels = cfg.get('IN_CHANNELS', 4)
|
||||
self.out_channels = self.in_channels * 2 if self.pred_sigma else self.in_channels
|
||||
self.patch_size = cfg.get('PATCH_SIZE', 2)
|
||||
self.num_heads = cfg.get('NUM_HEADS', 16)
|
||||
self.hidden_size = cfg.get('HIDDEN_SIZE', 1152)
|
||||
self.y_channels = cfg.get('Y_CHANNELS', 4096)
|
||||
self.drop_path = cfg.get('DROP_PATH', 0.)
|
||||
self.depth = cfg.get('DEPTH', 28)
|
||||
self.mlp_ratio = cfg.get('MLP_RATIO', 4.0)
|
||||
self.use_grad_checkpoint = cfg.get('USE_GRAD_CHECKPOINT', False)
|
||||
self.attention_backend = cfg.get('ATTENTION_BACKEND', None)
|
||||
self.max_seq_len = cfg.get('MAX_SEQ_LEN', 1024)
|
||||
self.qk_norm = cfg.get('QK_NORM', False)
|
||||
self.ignore_keys = cfg.get('IGNORE_KEYS', [])
|
||||
assert (self.hidden_size % self.num_heads
|
||||
) == 0 and (self.hidden_size // self.num_heads) % 2 == 0
|
||||
d = self.hidden_size // self.num_heads
|
||||
self.freqs = torch.cat(
|
||||
[
|
||||
rope_params(self.max_seq_len, d - 4 * (d // 6)), # T (~1/3)
|
||||
rope_params(self.max_seq_len, 2 * (d // 6)), # H (~1/3)
|
||||
rope_params(self.max_seq_len, 2 * (d // 6)) # W (~1/3)
|
||||
],
|
||||
dim=1)
|
||||
|
||||
# init embedder
|
||||
self.x_embedder = PatchEmbed(self.patch_size,
|
||||
self.in_channels + 1,
|
||||
self.hidden_size,
|
||||
bias=True,
|
||||
flatten=False)
|
||||
self.t_embedder = TimestepEmbedder(self.hidden_size)
|
||||
self.y_embedder = Mlp(in_features=self.y_channels,
|
||||
hidden_features=self.hidden_size,
|
||||
out_features=self.hidden_size,
|
||||
act_layer=lambda: nn.GELU(approximate='tanh'),
|
||||
drop=0)
|
||||
self.t_block = nn.Sequential(
|
||||
nn.SiLU(),
|
||||
nn.Linear(self.hidden_size, 6 * self.hidden_size, bias=True))
|
||||
# init blocks
|
||||
drop_path = [
|
||||
x.item() for x in torch.linspace(0, self.drop_path, self.depth)
|
||||
]
|
||||
self.blocks = nn.ModuleList([
|
||||
ACEBlock(self.hidden_size,
|
||||
self.num_heads,
|
||||
mlp_ratio=self.mlp_ratio,
|
||||
drop_path=drop_path[i],
|
||||
window_size=self.window_size
|
||||
if i in self.window_block_indexes else 0,
|
||||
backend=self.attention_backend,
|
||||
use_condition=True,
|
||||
qk_norm=self.qk_norm) for i in range(self.depth)
|
||||
])
|
||||
self.final_layer = T2IFinalLayer(self.hidden_size, self.patch_size,
|
||||
self.out_channels)
|
||||
self.initialize_weights()
|
||||
|
||||
def load_pretrained_model(self, pretrained_model):
|
||||
if pretrained_model:
|
||||
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
||||
model = torch.load(local_path, map_location='cpu')
|
||||
if 'state_dict' in model:
|
||||
model = model['state_dict']
|
||||
new_ckpt = OrderedDict()
|
||||
for k, v in model.items():
|
||||
if self.ignore_keys is not None:
|
||||
if (isinstance(self.ignore_keys, str) and re.match(self.ignore_keys, k)) or \
|
||||
(isinstance(self.ignore_keys, list) and k in self.ignore_keys):
|
||||
continue
|
||||
k = k.replace('.cross_attn.q_linear.', '.cross_attn.q.')
|
||||
k = k.replace('.cross_attn.proj.',
|
||||
'.cross_attn.o.').replace(
|
||||
'.attn.proj.', '.attn.o.')
|
||||
if '.cross_attn.kv_linear.' in k:
|
||||
k_p, v_p = torch.split(v, v.shape[0] // 2)
|
||||
new_ckpt[k.replace('.cross_attn.kv_linear.',
|
||||
'.cross_attn.k.')] = k_p
|
||||
new_ckpt[k.replace('.cross_attn.kv_linear.',
|
||||
'.cross_attn.v.')] = v_p
|
||||
elif '.attn.qkv.' in k:
|
||||
q_p, k_p, v_p = torch.split(v, v.shape[0] // 3)
|
||||
new_ckpt[k.replace('.attn.qkv.', '.attn.q.')] = q_p
|
||||
new_ckpt[k.replace('.attn.qkv.', '.attn.k.')] = k_p
|
||||
new_ckpt[k.replace('.attn.qkv.', '.attn.v.')] = v_p
|
||||
elif 'y_embedder.y_proj.' in k:
|
||||
new_ckpt[k.replace('y_embedder.y_proj.',
|
||||
'y_embedder.')] = v
|
||||
elif k in ('x_embedder.proj.weight'):
|
||||
model_p = self.state_dict()[k]
|
||||
if v.shape != model_p.shape:
|
||||
model_p.zero_()
|
||||
model_p[:, :4, :, :].copy_(v)
|
||||
new_ckpt[k] = torch.nn.parameter.Parameter(model_p)
|
||||
else:
|
||||
new_ckpt[k] = v
|
||||
elif k in ('x_embedder.proj.bias'):
|
||||
new_ckpt[k] = v
|
||||
else:
|
||||
new_ckpt[k] = v
|
||||
missing, unexpected = self.load_state_dict(new_ckpt,
|
||||
strict=False)
|
||||
print(
|
||||
f'Restored from {pretrained_model} with {len(missing)} missing and {len(unexpected)} unexpected keys'
|
||||
)
|
||||
if len(missing) > 0:
|
||||
print(f'Missing Keys:\n {missing}')
|
||||
if len(unexpected) > 0:
|
||||
print(f'\nUnexpected Keys:\n {unexpected}')
|
||||
|
||||
def forward(self,
|
||||
x,
|
||||
t=None,
|
||||
cond=dict(),
|
||||
mask=None,
|
||||
text_position_embeddings=None,
|
||||
gc_seg=-1,
|
||||
**kwargs):
|
||||
if self.freqs.device != x.device:
|
||||
self.freqs = self.freqs.to(x.device)
|
||||
if isinstance(cond, dict):
|
||||
context = cond.get('crossattn', None)
|
||||
else:
|
||||
context = cond
|
||||
if text_position_embeddings is not None:
|
||||
# default use the text_position_embeddings in state_dict
|
||||
# if state_dict doesn't including this key, use the arg: text_position_embeddings
|
||||
proj_position_embeddings = self.y_embedder(
|
||||
text_position_embeddings)
|
||||
else:
|
||||
proj_position_embeddings = None
|
||||
|
||||
ctx_batch, txt_lens = [], []
|
||||
if mask is not None and isinstance(mask, list):
|
||||
for ctx, ctx_mask in zip(context, mask):
|
||||
for frame_id, one_ctx in enumerate(zip(ctx, ctx_mask)):
|
||||
u, m = one_ctx
|
||||
t_len = m.flatten().sum() # l
|
||||
u = u[:t_len]
|
||||
u = self.y_embedder(u)
|
||||
if frame_id == 0:
|
||||
u = u + proj_position_embeddings[
|
||||
len(ctx) -
|
||||
1] if proj_position_embeddings is not None else u
|
||||
else:
|
||||
u = u + proj_position_embeddings[
|
||||
frame_id -
|
||||
1] if proj_position_embeddings is not None else u
|
||||
ctx_batch.append(u)
|
||||
txt_lens.append(t_len)
|
||||
else:
|
||||
raise TypeError
|
||||
y = torch.cat(ctx_batch, dim=0)
|
||||
txt_lens = torch.LongTensor(txt_lens).to(x.device, non_blocking=True)
|
||||
|
||||
batch_frames = []
|
||||
for u, shape, m in zip(x, cond['x_shapes'], cond['x_mask']):
|
||||
u = u[:, :shape[0] * shape[1]].view(-1, shape[0], shape[1])
|
||||
m = torch.ones_like(u[[0], :, :]) if m is None else m.squeeze(0)
|
||||
batch_frames.append([torch.cat([u, m], dim=0).unsqueeze(0)])
|
||||
if 'edit' in cond:
|
||||
for i, (edit, edit_mask) in enumerate(
|
||||
zip(cond['edit'], cond['edit_mask'])):
|
||||
if edit is None:
|
||||
continue
|
||||
for u, m in zip(edit, edit_mask):
|
||||
u = u.squeeze(0)
|
||||
m = torch.ones_like(
|
||||
u[[0], :, :]) if m is None else m.squeeze(0)
|
||||
batch_frames[i].append(
|
||||
torch.cat([u, m], dim=0).unsqueeze(0))
|
||||
|
||||
patch_batch, shape_batch, self_x_len, cross_x_len = [], [], [], []
|
||||
for frames in batch_frames:
|
||||
patches, patch_shapes = [], []
|
||||
self_x_len.append(0)
|
||||
for frame_id, u in enumerate(frames):
|
||||
u = self.x_embedder(u)
|
||||
h, w = u.size(2), u.size(3)
|
||||
u = rearrange(u, '1 c h w -> (h w) c')
|
||||
if frame_id == 0:
|
||||
u = u + proj_position_embeddings[
|
||||
len(frames) -
|
||||
1] if proj_position_embeddings is not None else u
|
||||
else:
|
||||
u = u + proj_position_embeddings[
|
||||
frame_id -
|
||||
1] if proj_position_embeddings is not None else u
|
||||
patches.append(u)
|
||||
patch_shapes.append([h, w])
|
||||
cross_x_len.append(h * w) # b*s, 1
|
||||
self_x_len[-1] += h * w # b, 1
|
||||
# u = torch.cat(patches, dim=0)
|
||||
patch_batch.extend(patches)
|
||||
shape_batch.append(
|
||||
torch.LongTensor(patch_shapes).to(x.device, non_blocking=True))
|
||||
# repeat t to align with x
|
||||
t = torch.cat([t[i].repeat(l) for i, l in enumerate(self_x_len)])
|
||||
self_x_len, cross_x_len = (torch.LongTensor(self_x_len).to(
|
||||
x.device, non_blocking=True), torch.LongTensor(cross_x_len).to(
|
||||
x.device, non_blocking=True))
|
||||
# x = pad_sequence(tuple(patch_batch), batch_first=True) # b, s*max(cl), c
|
||||
x = torch.cat(patch_batch, dim=0)
|
||||
x_shapes = pad_sequence(tuple(shape_batch),
|
||||
batch_first=True) # b, max(len(frames)), 2
|
||||
t = self.t_embedder(t) # (N, D)
|
||||
t0 = self.t_block(t)
|
||||
# y = self.y_embedder(context)
|
||||
|
||||
kwargs = dict(y=y,
|
||||
t=t0,
|
||||
x_shapes=x_shapes,
|
||||
self_x_len=self_x_len,
|
||||
cross_x_len=cross_x_len,
|
||||
freqs=self.freqs,
|
||||
txt_lens=txt_lens)
|
||||
if self.use_grad_checkpoint and gc_seg >= 0:
|
||||
x = checkpoint_sequential(
|
||||
functions=[partial(block, **kwargs) for block in self.blocks],
|
||||
segments=gc_seg if gc_seg > 0 else len(self.blocks),
|
||||
input=x,
|
||||
use_reentrant=False)
|
||||
else:
|
||||
for block in self.blocks:
|
||||
x = block(x, **kwargs)
|
||||
x = self.final_layer(x, t) # b*s*n, d
|
||||
outs, cur_length = [], 0
|
||||
p = self.patch_size
|
||||
for seq_length, shape in zip(self_x_len, shape_batch):
|
||||
x_i = x[cur_length:cur_length + seq_length]
|
||||
h, w = shape[0].tolist()
|
||||
u = x_i[:h * w].view(h, w, p, p, -1)
|
||||
u = rearrange(u, 'h w p q c -> (h p w q) c'
|
||||
) # dump into sequence for following tensor ops
|
||||
cur_length = cur_length + seq_length
|
||||
outs.append(u)
|
||||
x = pad_sequence(tuple(outs), batch_first=True).permute(0, 2, 1)
|
||||
if self.pred_sigma:
|
||||
return x.chunk(2, dim=1)[0]
|
||||
else:
|
||||
return x
|
||||
|
||||
def initialize_weights(self):
|
||||
# Initialize transformer layers:
|
||||
def _basic_init(module):
|
||||
if isinstance(module, nn.Linear):
|
||||
torch.nn.init.xavier_uniform_(module.weight)
|
||||
if module.bias is not None:
|
||||
nn.init.constant_(module.bias, 0)
|
||||
|
||||
self.apply(_basic_init)
|
||||
# Initialize patch_embed like nn.Linear (instead of nn.Conv2d):
|
||||
w = self.x_embedder.proj.weight.data
|
||||
nn.init.xavier_uniform_(w.view([w.shape[0], -1]))
|
||||
# Initialize timestep embedding MLP:
|
||||
nn.init.normal_(self.t_embedder.mlp[0].weight, std=0.02)
|
||||
nn.init.normal_(self.t_embedder.mlp[2].weight, std=0.02)
|
||||
nn.init.normal_(self.t_block[1].weight, std=0.02)
|
||||
# Initialize caption embedding MLP:
|
||||
if hasattr(self, 'y_embedder'):
|
||||
nn.init.normal_(self.y_embedder.fc1.weight, std=0.02)
|
||||
nn.init.normal_(self.y_embedder.fc2.weight, std=0.02)
|
||||
# Zero-out adaLN modulation layers
|
||||
for block in self.blocks:
|
||||
nn.init.constant_(block.cross_attn.o.weight, 0)
|
||||
nn.init.constant_(block.cross_attn.o.bias, 0)
|
||||
# Zero-out output layers:
|
||||
nn.init.constant_(self.final_layer.linear.weight, 0)
|
||||
nn.init.constant_(self.final_layer.linear.bias, 0)
|
||||
|
||||
@property
|
||||
def dtype(self):
|
||||
return next(self.parameters()).dtype
|
||||
|
||||
@staticmethod
|
||||
def get_config_template():
|
||||
return dict_to_yaml('BACKBONE',
|
||||
__class__.__name__,
|
||||
ACE.para_dict,
|
||||
set_name=True)
|
||||
@@ -0,0 +1,205 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import math
|
||||
import warnings
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
|
||||
from scepter.modules.model.backbone.transformer.attention import RMSNorm
|
||||
from scepter.modules.model.backbone.transformer.layers import (DropPath, Mlp,
|
||||
modulate)
|
||||
from scepter.modules.model.backbone.transformer.pos_embed import \
|
||||
rope_apply_multires as rope_apply
|
||||
|
||||
try:
|
||||
from flash_attn import (flash_attn_varlen_func)
|
||||
FLASHATTN_IS_AVAILABLE = True
|
||||
except ImportError as e:
|
||||
FLASHATTN_IS_AVAILABLE = False
|
||||
flash_attn_varlen_func = None
|
||||
warnings.warn(f'{e}')
|
||||
|
||||
|
||||
class ACEBlock(nn.Module):
|
||||
def __init__(self,
|
||||
hidden_size,
|
||||
num_heads,
|
||||
mlp_ratio=4.0,
|
||||
drop_path=0.,
|
||||
window_size=0,
|
||||
backend=None,
|
||||
use_condition=True,
|
||||
qk_norm=False,
|
||||
**block_kwargs):
|
||||
super().__init__()
|
||||
self.hidden_size = hidden_size
|
||||
self.use_condition = use_condition
|
||||
self.norm1 = nn.LayerNorm(hidden_size,
|
||||
elementwise_affine=False,
|
||||
eps=1e-6)
|
||||
self.attn = MultiHeadAttention(hidden_size,
|
||||
num_heads=num_heads,
|
||||
qkv_bias=True,
|
||||
backend=backend,
|
||||
qk_norm=qk_norm,
|
||||
**block_kwargs)
|
||||
if self.use_condition:
|
||||
self.cross_attn = MultiHeadAttention(hidden_size,
|
||||
context_dim=hidden_size,
|
||||
num_heads=num_heads,
|
||||
qkv_bias=True,
|
||||
backend=backend,
|
||||
qk_norm=qk_norm,
|
||||
**block_kwargs)
|
||||
self.norm2 = nn.LayerNorm(hidden_size,
|
||||
elementwise_affine=False,
|
||||
eps=1e-6)
|
||||
# to be compatible with lower version pytorch
|
||||
approx_gelu = lambda: nn.GELU(approximate='tanh')
|
||||
self.mlp = Mlp(in_features=hidden_size,
|
||||
hidden_features=int(hidden_size * mlp_ratio),
|
||||
act_layer=approx_gelu,
|
||||
drop=0)
|
||||
self.drop_path = DropPath(
|
||||
drop_path) if drop_path > 0. else nn.Identity()
|
||||
self.window_size = window_size
|
||||
self.scale_shift_table = nn.Parameter(
|
||||
torch.randn(6, hidden_size) / hidden_size**0.5)
|
||||
|
||||
def forward(self, x, y, t, **kwargs):
|
||||
B = x.size(0)
|
||||
shift_msa, scale_msa, gate_msa, shift_mlp, scale_mlp, gate_mlp = (
|
||||
self.scale_shift_table[None] + t.reshape(B, 6, -1)).chunk(6, dim=1)
|
||||
shift_msa, scale_msa, gate_msa, shift_mlp, scale_mlp, gate_mlp = (
|
||||
shift_msa.squeeze(1), scale_msa.squeeze(1), gate_msa.squeeze(1),
|
||||
shift_mlp.squeeze(1), scale_mlp.squeeze(1), gate_mlp.squeeze(1))
|
||||
x = x + self.drop_path(gate_msa * self.attn(
|
||||
modulate(self.norm1(x), shift_msa, scale_msa, unsqueeze=False), **
|
||||
kwargs))
|
||||
if self.use_condition:
|
||||
x = x + self.cross_attn(x, context=y, **kwargs)
|
||||
|
||||
x = x + self.drop_path(gate_mlp * self.mlp(
|
||||
modulate(self.norm2(x), shift_mlp, scale_mlp, unsqueeze=False)))
|
||||
return x
|
||||
|
||||
|
||||
class MultiHeadAttention(nn.Module):
|
||||
def __init__(self,
|
||||
dim,
|
||||
context_dim=None,
|
||||
num_heads=None,
|
||||
head_dim=None,
|
||||
attn_drop=0.0,
|
||||
qkv_bias=False,
|
||||
dropout=0.0,
|
||||
backend=None,
|
||||
qk_norm=False,
|
||||
eps=1e-6,
|
||||
**block_kwargs):
|
||||
super().__init__()
|
||||
# consider head_dim first, then num_heads
|
||||
num_heads = dim // head_dim if head_dim else num_heads
|
||||
head_dim = dim // num_heads
|
||||
assert num_heads * head_dim == dim
|
||||
context_dim = context_dim or dim
|
||||
self.dim = dim
|
||||
self.context_dim = context_dim
|
||||
self.num_heads = num_heads
|
||||
self.head_dim = head_dim
|
||||
self.scale = math.pow(head_dim, -0.25)
|
||||
# layers
|
||||
self.q = nn.Linear(dim, dim, bias=qkv_bias)
|
||||
self.k = nn.Linear(context_dim, dim, bias=qkv_bias)
|
||||
self.v = nn.Linear(context_dim, dim, bias=qkv_bias)
|
||||
self.o = nn.Linear(dim, dim)
|
||||
self.norm_q = RMSNorm(dim, eps=eps) if qk_norm else nn.Identity()
|
||||
self.norm_k = RMSNorm(dim, eps=eps) if qk_norm else nn.Identity()
|
||||
|
||||
self.dropout = nn.Dropout(dropout)
|
||||
self.attention_op = None
|
||||
self.attn_drop = nn.Dropout(attn_drop)
|
||||
self.backend = backend
|
||||
assert self.backend in ('flash_attn', 'xformer_attn', 'pytorch_attn',
|
||||
None)
|
||||
if FLASHATTN_IS_AVAILABLE and self.backend in ('flash_attn', None):
|
||||
self.backend = 'flash_attn'
|
||||
self.softmax_scale = block_kwargs.get('softmax_scale', None)
|
||||
self.causal = block_kwargs.get('causal', False)
|
||||
self.window_size = block_kwargs.get('window_size', (-1, -1))
|
||||
self.deterministic = block_kwargs.get('deterministic', False)
|
||||
else:
|
||||
raise NotImplementedError
|
||||
|
||||
def flash_attn(self, x, context=None, **kwargs):
|
||||
'''
|
||||
The implementation will be very slow when mask is not None,
|
||||
because we need rearange the x/context features according to mask.
|
||||
Args:
|
||||
x:
|
||||
context:
|
||||
mask:
|
||||
**kwargs:
|
||||
Returns: x
|
||||
'''
|
||||
dtype = kwargs.get('dtype', torch.float16)
|
||||
|
||||
def half(x):
|
||||
return x if x.dtype in [torch.float16, torch.bfloat16
|
||||
] else x.to(dtype)
|
||||
|
||||
x_shapes = kwargs['x_shapes']
|
||||
freqs = kwargs['freqs']
|
||||
self_x_len = kwargs['self_x_len']
|
||||
cross_x_len = kwargs['cross_x_len']
|
||||
txt_lens = kwargs['txt_lens']
|
||||
n, d = self.num_heads, self.head_dim
|
||||
|
||||
if context is None:
|
||||
# self-attn
|
||||
q = self.norm_q(self.q(x)).view(-1, n, d)
|
||||
k = self.norm_q(self.k(x)).view(-1, n, d)
|
||||
v = self.v(x).view(-1, n, d)
|
||||
q = rope_apply(q, self_x_len, x_shapes, freqs, pad=False)
|
||||
k = rope_apply(k, self_x_len, x_shapes, freqs, pad=False)
|
||||
q_lens = k_lens = self_x_len
|
||||
else:
|
||||
# cross-attn
|
||||
q = self.norm_q(self.q(x)).view(-1, n, d)
|
||||
k = self.norm_q(self.k(context)).view(-1, n, d)
|
||||
v = self.v(context).view(-1, n, d)
|
||||
q_lens = cross_x_len
|
||||
k_lens = txt_lens
|
||||
|
||||
cu_seqlens_q = torch.cat([q_lens.new_zeros([1]),
|
||||
q_lens]).cumsum(0, dtype=torch.int32)
|
||||
cu_seqlens_k = torch.cat([k_lens.new_zeros([1]),
|
||||
k_lens]).cumsum(0, dtype=torch.int32)
|
||||
max_seqlen_q = q_lens.max()
|
||||
max_seqlen_k = k_lens.max()
|
||||
|
||||
out_dtype = q.dtype
|
||||
q, k, v = half(q), half(k), half(v)
|
||||
x = flash_attn_varlen_func(q,
|
||||
k,
|
||||
v,
|
||||
cu_seqlens_q=cu_seqlens_q,
|
||||
cu_seqlens_k=cu_seqlens_k,
|
||||
max_seqlen_q=max_seqlen_q,
|
||||
max_seqlen_k=max_seqlen_k,
|
||||
dropout_p=self.attn_drop.p,
|
||||
softmax_scale=self.softmax_scale,
|
||||
causal=self.causal,
|
||||
window_size=self.window_size,
|
||||
deterministic=self.deterministic)
|
||||
|
||||
x = x.type(out_dtype)
|
||||
x = x.reshape(-1, n * d)
|
||||
x = self.o(x)
|
||||
x = self.dropout(x)
|
||||
return x
|
||||
|
||||
def forward(self, x, context=None, **kwargs):
|
||||
x = getattr(self, self.backend)(x, context=context, **kwargs)
|
||||
return x
|
||||
@@ -1 +1,3 @@
|
||||
from .flux import Flux
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from .flux import Flux
|
||||
|
||||
@@ -1,3 +1,5 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import math
|
||||
from functools import partial
|
||||
|
||||
@@ -11,9 +13,9 @@ from scepter.modules.utils.file_system import FS
|
||||
from torch import Tensor, nn
|
||||
from torch.utils.checkpoint import checkpoint_sequential
|
||||
|
||||
from .layers import (DoubleStreamBlock, EmbedND, LastLayer,
|
||||
MLPEmbedder, SingleStreamBlock,
|
||||
timestep_embedding)
|
||||
from .layers import (DoubleStreamBlock, EmbedND, LastLayer, MLPEmbedder,
|
||||
SingleStreamBlock, timestep_embedding)
|
||||
|
||||
|
||||
@BACKBONES.register_class()
|
||||
class Flux(BaseModel):
|
||||
@@ -21,73 +23,72 @@ class Flux(BaseModel):
|
||||
Transformer backbone Diffusion model with RoPE.
|
||||
"""
|
||||
para_dict = {
|
||||
"IN_CHANNELS": {
|
||||
"value": 64,
|
||||
"description": "model's input channels."
|
||||
'IN_CHANNELS': {
|
||||
'value': 64,
|
||||
'description': "model's input channels."
|
||||
},
|
||||
"OUT_CHANNELS": {
|
||||
"value": 64,
|
||||
"description": "model's output channels."
|
||||
'OUT_CHANNELS': {
|
||||
'value': 64,
|
||||
'description': "model's output channels."
|
||||
},
|
||||
"HIDDEN_SIZE": {
|
||||
"value": 1024,
|
||||
"description": "model's hidden size."
|
||||
'HIDDEN_SIZE': {
|
||||
'value': 1024,
|
||||
'description': "model's hidden size."
|
||||
},
|
||||
"NUM_HEADS": {
|
||||
"value": 16,
|
||||
"description": "number of heads in the transformer."
|
||||
'NUM_HEADS': {
|
||||
'value': 16,
|
||||
'description': 'number of heads in the transformer.'
|
||||
},
|
||||
"AXES_DIM": {
|
||||
"value": [16, 56, 56],
|
||||
"description": "dimensions of the axes of the positional encoding."
|
||||
'AXES_DIM': {
|
||||
'value': [16, 56, 56],
|
||||
'description': 'dimensions of the axes of the positional encoding.'
|
||||
},
|
||||
"THETA": {
|
||||
"value": 10_000,
|
||||
"description": "theta for positional encoding."
|
||||
'THETA': {
|
||||
'value': 10_000,
|
||||
'description': 'theta for positional encoding.'
|
||||
},
|
||||
"VEC_IN_DIM": {
|
||||
"value": 768,
|
||||
"description": "dimension of the vector input."
|
||||
'VEC_IN_DIM': {
|
||||
'value': 768,
|
||||
'description': 'dimension of the vector input.'
|
||||
},
|
||||
"GUIDANCE_EMBED": {
|
||||
"value": False,
|
||||
"description": "whether to use guidance embedding."
|
||||
'GUIDANCE_EMBED': {
|
||||
'value': False,
|
||||
'description': 'whether to use guidance embedding.'
|
||||
},
|
||||
"CONTEXT_IN_DIM": {
|
||||
"value": 4096,
|
||||
"description": "dimension of the context input."
|
||||
'CONTEXT_IN_DIM': {
|
||||
'value': 4096,
|
||||
'description': 'dimension of the context input.'
|
||||
},
|
||||
"MLP_RATIO": {
|
||||
"value": 4.0,
|
||||
"description": "ratio of mlp hidden size to hidden size."
|
||||
'MLP_RATIO': {
|
||||
'value': 4.0,
|
||||
'description': 'ratio of mlp hidden size to hidden size.'
|
||||
},
|
||||
"QKV_BIAS": {
|
||||
"value": True,
|
||||
"description": "whether to use bias in qkv projection."
|
||||
'QKV_BIAS': {
|
||||
'value': True,
|
||||
'description': 'whether to use bias in qkv projection.'
|
||||
},
|
||||
"DEPTH": {
|
||||
"value": 19,
|
||||
"description": "number of transformer blocks."
|
||||
'DEPTH': {
|
||||
'value': 19,
|
||||
'description': 'number of transformer blocks.'
|
||||
},
|
||||
"DEPTH_SINGLE_BLOCKS": {
|
||||
"value": 38,
|
||||
"description": "number of transformer blocks in the single stream block."
|
||||
'DEPTH_SINGLE_BLOCKS': {
|
||||
'value':
|
||||
38,
|
||||
'description':
|
||||
'number of transformer blocks in the single stream block.'
|
||||
},
|
||||
"USE_GRAD_CHECKPOINT": {
|
||||
"value": False,
|
||||
"description": "whether to use gradient checkpointing."
|
||||
'USE_GRAD_CHECKPOINT': {
|
||||
'value': False,
|
||||
'description': 'whether to use gradient checkpointing.'
|
||||
}
|
||||
}
|
||||
def __init__(
|
||||
self,
|
||||
cfg,
|
||||
logger = None
|
||||
):
|
||||
|
||||
def __init__(self, cfg, logger=None):
|
||||
super().__init__(cfg, logger=logger)
|
||||
self.in_channels = cfg.IN_CHANNELS
|
||||
self.out_channels = cfg.get("OUT_CHANNELS", self.in_channels)
|
||||
hidden_size = cfg.get("HIDDEN_SIZE", 1024)
|
||||
num_heads = cfg.get("NUM_HEADS", 16)
|
||||
self.out_channels = cfg.get('OUT_CHANNELS', self.in_channels)
|
||||
hidden_size = cfg.get('HIDDEN_SIZE', 1024)
|
||||
num_heads = cfg.get('NUM_HEADS', 16)
|
||||
axes_dim = cfg.AXES_DIM
|
||||
theta = cfg.THETA
|
||||
vec_in_dim = cfg.VEC_IN_DIM
|
||||
@@ -97,7 +98,7 @@ class Flux(BaseModel):
|
||||
qkv_bias = cfg.QKV_BIAS
|
||||
depth = cfg.DEPTH
|
||||
depth_single_blocks = cfg.DEPTH_SINGLE_BLOCKS
|
||||
self.use_grad_checkpoint = cfg.get("USE_GRAD_CHECKPOINT", False)
|
||||
self.use_grad_checkpoint = cfg.get('USE_GRAD_CHECKPOINT', False)
|
||||
|
||||
if hidden_size % num_heads != 0:
|
||||
raise ValueError(
|
||||
@@ -105,56 +106,54 @@ class Flux(BaseModel):
|
||||
)
|
||||
pe_dim = hidden_size // num_heads
|
||||
if sum(axes_dim) != pe_dim:
|
||||
raise ValueError(f"Got {axes_dim} but expected positional dim {pe_dim}")
|
||||
raise ValueError(
|
||||
f"Got {axes_dim} but expected positional dim {pe_dim}")
|
||||
self.hidden_size = hidden_size
|
||||
self.num_heads = num_heads
|
||||
self.pe_embedder = EmbedND(dim=pe_dim, theta=theta, axes_dim= axes_dim)
|
||||
self.pe_embedder = EmbedND(dim=pe_dim, theta=theta, axes_dim=axes_dim)
|
||||
self.img_in = nn.Linear(self.in_channels, self.hidden_size, bias=True)
|
||||
self.time_in = MLPEmbedder(in_dim=256, hidden_dim=self.hidden_size)
|
||||
self.vector_in = MLPEmbedder(vec_in_dim, self.hidden_size)
|
||||
self.guidance_in = (
|
||||
MLPEmbedder(in_dim=256, hidden_dim=self.hidden_size) if self.guidance_embed else nn.Identity()
|
||||
)
|
||||
self.guidance_in = (MLPEmbedder(in_dim=256,
|
||||
hidden_dim=self.hidden_size)
|
||||
if self.guidance_embed else nn.Identity())
|
||||
self.txt_in = nn.Linear(context_in_dim, self.hidden_size)
|
||||
|
||||
self.double_blocks = nn.ModuleList(
|
||||
[
|
||||
DoubleStreamBlock(
|
||||
self.hidden_size,
|
||||
self.num_heads,
|
||||
mlp_ratio=mlp_ratio,
|
||||
qkv_bias=qkv_bias,
|
||||
)
|
||||
for _ in range(depth)
|
||||
]
|
||||
)
|
||||
self.double_blocks = nn.ModuleList([
|
||||
DoubleStreamBlock(
|
||||
self.hidden_size,
|
||||
self.num_heads,
|
||||
mlp_ratio=mlp_ratio,
|
||||
qkv_bias=qkv_bias,
|
||||
) for _ in range(depth)
|
||||
])
|
||||
|
||||
self.single_blocks = nn.ModuleList(
|
||||
[
|
||||
SingleStreamBlock(self.hidden_size, self.num_heads, mlp_ratio=mlp_ratio)
|
||||
for _ in range(depth_single_blocks)
|
||||
]
|
||||
)
|
||||
self.single_blocks = nn.ModuleList([
|
||||
SingleStreamBlock(self.hidden_size,
|
||||
self.num_heads,
|
||||
mlp_ratio=mlp_ratio)
|
||||
for _ in range(depth_single_blocks)
|
||||
])
|
||||
|
||||
self.final_layer = LastLayer(self.hidden_size, 1, self.out_channels)
|
||||
|
||||
def prepare_input(self, x, context, y, x_shape=None):
|
||||
# x.shape [6, 16, 16, 16] target is [6, 16, 768, 1360]
|
||||
bs, c, h, w = x.shape
|
||||
x = rearrange(x, "b c (h ph) (w pw) -> b (h w) (c ph pw)", ph=2, pw=2)
|
||||
x = rearrange(x, 'b c (h ph) (w pw) -> b (h w) (c ph pw)', ph=2, pw=2)
|
||||
x_id = torch.zeros(h // 2, w // 2, 3)
|
||||
x_id[..., 1] = x_id[..., 1] + torch.arange(h // 2)[:, None]
|
||||
x_id[..., 2] = x_id[..., 2] + torch.arange(w // 2)[None, :]
|
||||
x_ids = repeat(x_id, "h w c -> b (h w) c", b=bs)
|
||||
x_ids = repeat(x_id, 'h w c -> b (h w) c', b=bs)
|
||||
txt_ids = torch.zeros(bs, context.shape[1], 3)
|
||||
return x, x_ids.to(x), context.to(x), txt_ids.to(x), y.to(x), h, w
|
||||
|
||||
def unpack(self, x: Tensor, height: int, width: int) -> Tensor:
|
||||
return rearrange(
|
||||
x,
|
||||
"b (h w) (c ph pw) -> b c (h ph) (w pw)",
|
||||
h=math.ceil(height/2),
|
||||
w=math.ceil(width/2),
|
||||
'b (h w) (c ph pw) -> b c (h ph) (w pw)',
|
||||
h=math.ceil(height / 2),
|
||||
w=math.ceil(width / 2),
|
||||
ph=2,
|
||||
pw=2,
|
||||
)
|
||||
@@ -163,38 +162,42 @@ class Flux(BaseModel):
|
||||
if next(self.parameters()).device.type == 'meta':
|
||||
map_location = we.device_id
|
||||
else:
|
||||
map_location = "cpu"
|
||||
map_location = 'cpu'
|
||||
if pretrained_model is not None:
|
||||
with FS.get_from(pretrained_model, wait_finish=True) as local_model:
|
||||
with FS.get_from(pretrained_model,
|
||||
wait_finish=True) as local_model:
|
||||
if local_model.endswith('safetensors'):
|
||||
from safetensors.torch import load_file as load_safetensors
|
||||
sd = load_safetensors(local_model, device=map_location)
|
||||
else:
|
||||
sd = torch.load(local_model, map_location=map_location)
|
||||
missing, unexpected = self.load_state_dict(sd, strict=False, assign=True)
|
||||
missing, unexpected = self.load_state_dict(sd,
|
||||
strict=False,
|
||||
assign=True)
|
||||
self.logger.info(
|
||||
f'Restored from {pretrained_model} with {len(missing)} missing and {len(unexpected)} unexpected keys'
|
||||
)
|
||||
if len(missing) > 0:
|
||||
self.logger.info(f'Missing Keys:\n {missing}')
|
||||
self.logger.info(f'Missing Keys:\n {missing}') # noqa
|
||||
if len(unexpected) > 0:
|
||||
self.logger.info(f'\nUnexpected Keys:\n {unexpected}')
|
||||
self.logger.info(f'\nUnexpected Keys:\n {unexpected}') # noqa
|
||||
|
||||
def forward(
|
||||
self,
|
||||
x: Tensor,
|
||||
t: Tensor,
|
||||
cond: dict = {},
|
||||
guidance: Tensor | None = None,
|
||||
gc_seg: int = 0
|
||||
) -> Tensor:
|
||||
x, x_ids, txt, txt_ids, y, h, w = self.prepare_input(x, cond["context"], cond["y"])
|
||||
def forward(self,
|
||||
x: Tensor,
|
||||
t: Tensor,
|
||||
cond: dict = {},
|
||||
guidance: Tensor | None = None,
|
||||
gc_seg: int = 0) -> Tensor:
|
||||
x, x_ids, txt, txt_ids, y, h, w = self.prepare_input(
|
||||
x, cond['context'], cond['y'])
|
||||
# running on sequences img
|
||||
x = self.img_in(x)
|
||||
vec = self.time_in(timestep_embedding(t, 256))
|
||||
if self.guidance_embed:
|
||||
if guidance is None:
|
||||
raise ValueError("Didn't get guidance strength for guidance distilled model.")
|
||||
raise ValueError(
|
||||
"Didn't get guidance strength for guidance distilled model."
|
||||
)
|
||||
vec = vec + self.guidance_in(timestep_embedding(guidance, 256))
|
||||
vec = vec + self.vector_in(y)
|
||||
txt = self.txt_in(txt)
|
||||
@@ -208,11 +211,12 @@ class Flux(BaseModel):
|
||||
x = torch.cat((txt, x), 1)
|
||||
if self.use_grad_checkpoint and gc_seg >= 0:
|
||||
x = checkpoint_sequential(
|
||||
functions=[partial(block, **kwargs) for block in self.double_blocks],
|
||||
functions=[
|
||||
partial(block, **kwargs) for block in self.double_blocks
|
||||
],
|
||||
segments=gc_seg if gc_seg > 0 else len(self.double_blocks),
|
||||
input=x,
|
||||
use_reentrant=False
|
||||
)
|
||||
use_reentrant=False)
|
||||
else:
|
||||
for block in self.double_blocks:
|
||||
x = block(x, **kwargs)
|
||||
@@ -224,16 +228,18 @@ class Flux(BaseModel):
|
||||
|
||||
if self.use_grad_checkpoint and gc_seg >= 0:
|
||||
x = checkpoint_sequential(
|
||||
functions=[partial(block, **kwargs) for block in self.single_blocks],
|
||||
functions=[
|
||||
partial(block, **kwargs) for block in self.single_blocks
|
||||
],
|
||||
segments=gc_seg if gc_seg > 0 else len(self.single_blocks),
|
||||
input=x,
|
||||
use_reentrant=False
|
||||
)
|
||||
use_reentrant=False)
|
||||
else:
|
||||
for block in self.single_blocks:
|
||||
x = block(x, **kwargs)
|
||||
x = x[:, txt.shape[1] :, ...]
|
||||
x = self.final_layer(x, vec) # (N, T, patch_size ** 2 * out_channels) 6 64 64
|
||||
x = x[:, txt.shape[1]:, ...]
|
||||
x = self.final_layer(
|
||||
x, vec) # (N, T, patch_size ** 2 * out_channels) 6 64 64
|
||||
x = self.unpack(x, h, w)
|
||||
return x
|
||||
|
||||
|
||||
@@ -1,37 +1,54 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from __future__ import annotations
|
||||
|
||||
import math
|
||||
from dataclasses import dataclass
|
||||
from torch import Tensor, nn
|
||||
|
||||
import torch
|
||||
from einops import rearrange, repeat
|
||||
from torch import Tensor
|
||||
from torch import Tensor, nn
|
||||
|
||||
|
||||
def attention(q: Tensor, k: Tensor, v: Tensor, pe: Tensor, mask: Tensor | None = None) -> Tensor:
|
||||
def attention(q: Tensor,
|
||||
k: Tensor,
|
||||
v: Tensor,
|
||||
pe: Tensor,
|
||||
mask: Tensor | None = None) -> Tensor:
|
||||
q, k = apply_rope(q, k, pe)
|
||||
x = torch.nn.functional.scaled_dot_product_attention(q, k, v, attn_mask=mask)
|
||||
x = torch.nn.functional.scaled_dot_product_attention(q,
|
||||
k,
|
||||
v,
|
||||
attn_mask=mask)
|
||||
x = torch.nan_to_num(x, nan=0.0, posinf=1e10, neginf=-1e10)
|
||||
x = rearrange(x, "B H L D -> B L (H D)")
|
||||
x = rearrange(x, 'B H L D -> B L (H D)')
|
||||
return x
|
||||
|
||||
|
||||
def rope(pos: Tensor, dim: int, theta: int) -> Tensor:
|
||||
assert dim % 2 == 0
|
||||
scale = torch.arange(0, dim, 2, dtype=torch.float64, device=pos.device) / dim
|
||||
scale = torch.arange(0, dim, 2, dtype=torch.float64,
|
||||
device=pos.device) / dim
|
||||
omega = 1.0 / (theta**scale)
|
||||
out = torch.einsum("...n,d->...nd", pos, omega)
|
||||
out = torch.stack([torch.cos(out), -torch.sin(out), torch.sin(out), torch.cos(out)], dim=-1)
|
||||
out = rearrange(out, "b n d (i j) -> b n d i j", i=2, j=2)
|
||||
out = torch.einsum('...n,d->...nd', pos, omega)
|
||||
out = torch.stack(
|
||||
[torch.cos(out), -torch.sin(out),
|
||||
torch.sin(out),
|
||||
torch.cos(out)],
|
||||
dim=-1)
|
||||
out = rearrange(out, 'b n d (i j) -> b n d i j', i=2, j=2)
|
||||
return out.float()
|
||||
|
||||
|
||||
def apply_rope(xq: Tensor, xk: Tensor, freqs_cis: Tensor) -> tuple[Tensor, Tensor]:
|
||||
def apply_rope(xq: Tensor, xk: Tensor,
|
||||
freqs_cis: Tensor) -> tuple[Tensor, Tensor]:
|
||||
xq_ = xq.float().reshape(*xq.shape[:-1], -1, 1, 2)
|
||||
xk_ = xk.float().reshape(*xk.shape[:-1], -1, 1, 2)
|
||||
xq_out = freqs_cis[..., 0] * xq_[..., 0] + freqs_cis[..., 1] * xq_[..., 1]
|
||||
xk_out = freqs_cis[..., 0] * xk_[..., 0] + freqs_cis[..., 1] * xk_[..., 1]
|
||||
return xq_out.reshape(*xq.shape).type_as(xq), xk_out.reshape(*xk.shape).type_as(xk)
|
||||
return xq_out.reshape(*xq.shape).type_as(xq), xk_out.reshape(
|
||||
*xk.shape).type_as(xk)
|
||||
|
||||
|
||||
class EmbedND(nn.Module):
|
||||
def __init__(self, dim: int, theta: int, axes_dim: list[int]):
|
||||
@@ -43,14 +60,20 @@ class EmbedND(nn.Module):
|
||||
def forward(self, ids: Tensor) -> Tensor:
|
||||
n_axes = ids.shape[-1]
|
||||
emb = torch.cat(
|
||||
[rope(ids[..., i], self.axes_dim[i], self.theta) for i in range(n_axes)],
|
||||
[
|
||||
rope(ids[..., i], self.axes_dim[i], self.theta)
|
||||
for i in range(n_axes)
|
||||
],
|
||||
dim=-3,
|
||||
)
|
||||
|
||||
return emb.unsqueeze(1)
|
||||
|
||||
|
||||
def timestep_embedding(t: Tensor, dim, max_period=10000, time_factor: float = 1000.0):
|
||||
def timestep_embedding(t: Tensor,
|
||||
dim,
|
||||
max_period=10000,
|
||||
time_factor: float = 1000.0):
|
||||
"""
|
||||
Create sinusoidal timestep embeddings.
|
||||
:param t: a 1-D Tensor of N indices, one per batch element.
|
||||
@@ -61,14 +84,15 @@ def timestep_embedding(t: Tensor, dim, max_period=10000, time_factor: float = 10
|
||||
"""
|
||||
t = time_factor * t
|
||||
half = dim // 2
|
||||
freqs = torch.exp(-math.log(max_period) * torch.arange(start=0, end=half, dtype=torch.float32) / half).to(
|
||||
t.device
|
||||
)
|
||||
freqs = torch.exp(-math.log(max_period) *
|
||||
torch.arange(start=0, end=half, dtype=torch.float32) /
|
||||
half).to(t.device)
|
||||
|
||||
args = t[:, None].float() * freqs[None]
|
||||
embedding = torch.cat([torch.cos(args), torch.sin(args)], dim=-1)
|
||||
if dim % 2:
|
||||
embedding = torch.cat([embedding, torch.zeros_like(embedding[:, :1])], dim=-1)
|
||||
embedding = torch.cat(
|
||||
[embedding, torch.zeros_like(embedding[:, :1])], dim=-1)
|
||||
if torch.is_floating_point(t):
|
||||
embedding = embedding.to(t)
|
||||
return embedding
|
||||
@@ -103,7 +127,8 @@ class QKNorm(torch.nn.Module):
|
||||
self.query_norm = RMSNorm(dim)
|
||||
self.key_norm = RMSNorm(dim)
|
||||
|
||||
def forward(self, q: Tensor, k: Tensor, v: Tensor) -> tuple[Tensor, Tensor]:
|
||||
def forward(self, q: Tensor, k: Tensor,
|
||||
v: Tensor) -> tuple[Tensor, Tensor]:
|
||||
q = self.query_norm(q)
|
||||
k = self.key_norm(k)
|
||||
return q.to(v), k.to(v)
|
||||
@@ -119,9 +144,15 @@ class SelfAttention(nn.Module):
|
||||
self.norm = QKNorm(head_dim)
|
||||
self.proj = nn.Linear(dim, dim)
|
||||
|
||||
def forward(self, x: Tensor, pe: Tensor, mask: Tensor | None = None) -> Tensor:
|
||||
def forward(self,
|
||||
x: Tensor,
|
||||
pe: Tensor,
|
||||
mask: Tensor | None = None) -> Tensor:
|
||||
qkv = self.qkv(x)
|
||||
q, k, v = rearrange(qkv, "B L (K H D) -> K B H L D", K=3, H=self.num_heads)
|
||||
q, k, v = rearrange(qkv,
|
||||
'B L (K H D) -> K B H L D',
|
||||
K=3,
|
||||
H=self.num_heads)
|
||||
q, k = self.norm(q, k, v)
|
||||
x = attention(q, k, v, pe=pe, mask=mask)
|
||||
x = self.proj(x)
|
||||
@@ -142,8 +173,11 @@ class Modulation(nn.Module):
|
||||
self.multiplier = 6 if double else 3
|
||||
self.lin = nn.Linear(dim, self.multiplier * dim, bias=True)
|
||||
|
||||
def forward(self, vec: Tensor) -> tuple[ModulationOut, ModulationOut | None]:
|
||||
out = self.lin(nn.functional.silu(vec))[:, None, :].chunk(self.multiplier, dim=-1)
|
||||
def forward(self,
|
||||
vec: Tensor) -> tuple[ModulationOut, ModulationOut | None]:
|
||||
out = self.lin(nn.functional.silu(vec))[:,
|
||||
None, :].chunk(self.multiplier,
|
||||
dim=-1)
|
||||
|
||||
return (
|
||||
ModulationOut(*out[:3]),
|
||||
@@ -152,35 +186,56 @@ class Modulation(nn.Module):
|
||||
|
||||
|
||||
class DoubleStreamBlock(nn.Module):
|
||||
def __init__(self, hidden_size: int, num_heads: int, mlp_ratio: float, qkv_bias: bool = False):
|
||||
def __init__(self,
|
||||
hidden_size: int,
|
||||
num_heads: int,
|
||||
mlp_ratio: float,
|
||||
qkv_bias: bool = False):
|
||||
super().__init__()
|
||||
|
||||
mlp_hidden_dim = int(hidden_size * mlp_ratio)
|
||||
self.num_heads = num_heads
|
||||
self.hidden_size = hidden_size
|
||||
self.img_mod = Modulation(hidden_size, double=True)
|
||||
self.img_norm1 = nn.LayerNorm(hidden_size, elementwise_affine=False, eps=1e-6)
|
||||
self.img_attn = SelfAttention(dim=hidden_size, num_heads=num_heads, qkv_bias=qkv_bias)
|
||||
self.img_norm1 = nn.LayerNorm(hidden_size,
|
||||
elementwise_affine=False,
|
||||
eps=1e-6)
|
||||
self.img_attn = SelfAttention(dim=hidden_size,
|
||||
num_heads=num_heads,
|
||||
qkv_bias=qkv_bias)
|
||||
|
||||
self.img_norm2 = nn.LayerNorm(hidden_size, elementwise_affine=False, eps=1e-6)
|
||||
self.img_norm2 = nn.LayerNorm(hidden_size,
|
||||
elementwise_affine=False,
|
||||
eps=1e-6)
|
||||
self.img_mlp = nn.Sequential(
|
||||
nn.Linear(hidden_size, mlp_hidden_dim, bias=True),
|
||||
nn.GELU(approximate="tanh"),
|
||||
nn.GELU(approximate='tanh'),
|
||||
nn.Linear(mlp_hidden_dim, hidden_size, bias=True),
|
||||
)
|
||||
|
||||
self.txt_mod = Modulation(hidden_size, double=True)
|
||||
self.txt_norm1 = nn.LayerNorm(hidden_size, elementwise_affine=False, eps=1e-6)
|
||||
self.txt_attn = SelfAttention(dim=hidden_size, num_heads=num_heads, qkv_bias=qkv_bias)
|
||||
self.txt_norm1 = nn.LayerNorm(hidden_size,
|
||||
elementwise_affine=False,
|
||||
eps=1e-6)
|
||||
self.txt_attn = SelfAttention(dim=hidden_size,
|
||||
num_heads=num_heads,
|
||||
qkv_bias=qkv_bias)
|
||||
|
||||
self.txt_norm2 = nn.LayerNorm(hidden_size, elementwise_affine=False, eps=1e-6)
|
||||
self.txt_norm2 = nn.LayerNorm(hidden_size,
|
||||
elementwise_affine=False,
|
||||
eps=1e-6)
|
||||
self.txt_mlp = nn.Sequential(
|
||||
nn.Linear(hidden_size, mlp_hidden_dim, bias=True),
|
||||
nn.GELU(approximate="tanh"),
|
||||
nn.GELU(approximate='tanh'),
|
||||
nn.Linear(mlp_hidden_dim, hidden_size, bias=True),
|
||||
)
|
||||
|
||||
def forward(self, x: Tensor, vec: Tensor, pe: Tensor, mask: Tensor = None, txt_length = None):
|
||||
def forward(self,
|
||||
x: Tensor,
|
||||
vec: Tensor,
|
||||
pe: Tensor,
|
||||
mask: Tensor = None,
|
||||
txt_length=None):
|
||||
img_mod1, img_mod2 = self.img_mod(vec)
|
||||
txt_mod1, txt_mod2 = self.txt_mod(vec)
|
||||
|
||||
@@ -190,13 +245,19 @@ class DoubleStreamBlock(nn.Module):
|
||||
img_modulated = self.img_norm1(img)
|
||||
img_modulated = (1 + img_mod1.scale) * img_modulated + img_mod1.shift
|
||||
img_qkv = self.img_attn.qkv(img_modulated)
|
||||
img_q, img_k, img_v = rearrange(img_qkv, "B L (K H D) -> K B H L D", K=3, H=self.num_heads)
|
||||
img_q, img_k, img_v = rearrange(img_qkv,
|
||||
'B L (K H D) -> K B H L D',
|
||||
K=3,
|
||||
H=self.num_heads)
|
||||
img_q, img_k = self.img_attn.norm(img_q, img_k, img_v)
|
||||
# prepare txt for attention
|
||||
txt_modulated = self.txt_norm1(txt)
|
||||
txt_modulated = (1 + txt_mod1.scale) * txt_modulated + txt_mod1.shift
|
||||
txt_qkv = self.txt_attn.qkv(txt_modulated)
|
||||
txt_q, txt_k, txt_v = rearrange(txt_qkv, "B L (K H D) -> K B H L D", K=3, H=self.num_heads)
|
||||
txt_q, txt_k, txt_v = rearrange(txt_qkv,
|
||||
'B L (K H D) -> K B H L D',
|
||||
K=3,
|
||||
H=self.num_heads)
|
||||
txt_q, txt_k = self.txt_attn.norm(txt_q, txt_k, txt_v)
|
||||
|
||||
# run actual attention
|
||||
@@ -205,16 +266,18 @@ class DoubleStreamBlock(nn.Module):
|
||||
v = torch.cat((txt_v, img_v), dim=2)
|
||||
if mask is not None:
|
||||
mask = repeat(mask, 'B L S-> B H L S', H=self.num_heads)
|
||||
attn = attention(q, k, v, pe=pe, mask = mask)
|
||||
txt_attn, img_attn = attn[:, : txt.shape[1]], attn[:, txt.shape[1] :]
|
||||
attn = attention(q, k, v, pe=pe, mask=mask)
|
||||
txt_attn, img_attn = attn[:, :txt.shape[1]], attn[:, txt.shape[1]:]
|
||||
|
||||
# calculate the img bloks
|
||||
img = img + img_mod1.gate * self.img_attn.proj(img_attn)
|
||||
img = img + img_mod2.gate * self.img_mlp((1 + img_mod2.scale) * self.img_norm2(img) + img_mod2.shift)
|
||||
img = img + img_mod2.gate * self.img_mlp(
|
||||
(1 + img_mod2.scale) * self.img_norm2(img) + img_mod2.shift)
|
||||
|
||||
# calculate the txt bloks
|
||||
txt = txt + txt_mod1.gate * self.txt_attn.proj(txt_attn)
|
||||
txt = txt + txt_mod2.gate * self.txt_mlp((1 + txt_mod2.scale) * self.txt_norm2(txt) + txt_mod2.shift)
|
||||
txt = txt + txt_mod2.gate * self.txt_mlp(
|
||||
(1 + txt_mod2.scale) * self.txt_norm2(txt) + txt_mod2.shift)
|
||||
x = torch.cat((txt, img), 1)
|
||||
return x
|
||||
|
||||
@@ -224,7 +287,6 @@ class SingleStreamBlock(nn.Module):
|
||||
A DiT block with parallel linear layers as described in
|
||||
https://arxiv.org/abs/2302.05442 and adapted modulation interface.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
hidden_size: int,
|
||||
@@ -240,29 +302,42 @@ class SingleStreamBlock(nn.Module):
|
||||
|
||||
self.mlp_hidden_dim = int(hidden_size * mlp_ratio)
|
||||
# qkv and mlp_in
|
||||
self.linear1 = nn.Linear(hidden_size, hidden_size * 3 + self.mlp_hidden_dim)
|
||||
self.linear1 = nn.Linear(hidden_size,
|
||||
hidden_size * 3 + self.mlp_hidden_dim)
|
||||
# proj and mlp_out
|
||||
self.linear2 = nn.Linear(hidden_size + self.mlp_hidden_dim, hidden_size)
|
||||
self.linear2 = nn.Linear(hidden_size + self.mlp_hidden_dim,
|
||||
hidden_size)
|
||||
|
||||
self.norm = QKNorm(head_dim)
|
||||
|
||||
self.hidden_size = hidden_size
|
||||
self.pre_norm = nn.LayerNorm(hidden_size, elementwise_affine=False, eps=1e-6)
|
||||
self.pre_norm = nn.LayerNorm(hidden_size,
|
||||
elementwise_affine=False,
|
||||
eps=1e-6)
|
||||
|
||||
self.mlp_act = nn.GELU(approximate="tanh")
|
||||
self.mlp_act = nn.GELU(approximate='tanh')
|
||||
self.modulation = Modulation(hidden_size, double=False)
|
||||
|
||||
def forward(self, x: Tensor, vec: Tensor, pe: Tensor, mask: Tensor = None) -> Tensor:
|
||||
def forward(self,
|
||||
x: Tensor,
|
||||
vec: Tensor,
|
||||
pe: Tensor,
|
||||
mask: Tensor = None) -> Tensor:
|
||||
mod, _ = self.modulation(vec)
|
||||
x_mod = (1 + mod.scale) * self.pre_norm(x) + mod.shift
|
||||
qkv, mlp = torch.split(self.linear1(x_mod), [3 * self.hidden_size, self.mlp_hidden_dim], dim=-1)
|
||||
qkv, mlp = torch.split(self.linear1(x_mod),
|
||||
[3 * self.hidden_size, self.mlp_hidden_dim],
|
||||
dim=-1)
|
||||
|
||||
q, k, v = rearrange(qkv, "B L (K H D) -> K B H L D", K=3, H=self.num_heads)
|
||||
q, k, v = rearrange(qkv,
|
||||
'B L (K H D) -> K B H L D',
|
||||
K=3,
|
||||
H=self.num_heads)
|
||||
q, k = self.norm(q, k, v)
|
||||
if mask is not None:
|
||||
mask = repeat(mask, 'B L S-> B H L S', H=self.num_heads)
|
||||
# compute attention
|
||||
attn = attention(q, k, v, pe=pe, mask = mask)
|
||||
attn = attention(q, k, v, pe=pe, mask=mask)
|
||||
# compute activation in mlp stream, cat again and run second linear layer
|
||||
output = self.linear2(torch.cat((attn, self.mlp_act(mlp)), 2))
|
||||
return x + mod.gate * output
|
||||
@@ -271,9 +346,14 @@ class SingleStreamBlock(nn.Module):
|
||||
class LastLayer(nn.Module):
|
||||
def __init__(self, hidden_size: int, patch_size: int, out_channels: int):
|
||||
super().__init__()
|
||||
self.norm_final = nn.LayerNorm(hidden_size, elementwise_affine=False, eps=1e-6)
|
||||
self.linear = nn.Linear(hidden_size, patch_size * patch_size * out_channels, bias=True)
|
||||
self.adaLN_modulation = nn.Sequential(nn.SiLU(), nn.Linear(hidden_size, 2 * hidden_size, bias=True))
|
||||
self.norm_final = nn.LayerNorm(hidden_size,
|
||||
elementwise_affine=False,
|
||||
eps=1e-6)
|
||||
self.linear = nn.Linear(hidden_size,
|
||||
patch_size * patch_size * out_channels,
|
||||
bias=True)
|
||||
self.adaLN_modulation = nn.Sequential(
|
||||
nn.SiLU(), nn.Linear(hidden_size, 2 * hidden_size, bias=True))
|
||||
|
||||
def forward(self, x: Tensor, vec: Tensor) -> Tensor:
|
||||
shift, scale = self.adaLN_modulation(vec).chunk(2, dim=1)
|
||||
|
||||
@@ -1,2 +1,3 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from .sd3 import MMDiT
|
||||
|
||||
@@ -5,12 +5,11 @@
|
||||
# diffusers: https://github.com/huggingface/diffusers
|
||||
# ComfyUI: https://github.com/comfyanonymous/ComfyUI
|
||||
|
||||
import logging
|
||||
import math
|
||||
import re
|
||||
from collections import OrderedDict
|
||||
from functools import partial
|
||||
from typing import Dict, Optional
|
||||
from typing import Optional
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
@@ -26,7 +25,7 @@ try:
|
||||
import xformers
|
||||
import xformers.ops
|
||||
XFORMERS_IS_AVAILBLE = True
|
||||
except:
|
||||
except Exception:
|
||||
XFORMERS_IS_AVAILBLE = False
|
||||
|
||||
BROKEN_XFORMERS = False
|
||||
@@ -35,7 +34,7 @@ try:
|
||||
# XFormers bug confirmed on all versions from 0.0.21 to 0.0.26 (q with bs bigger than 65535 gives CUDA error)
|
||||
BROKEN_XFORMERS = x_vers.startswith(
|
||||
'0.0.2') and not x_vers.startswith('0.0.20')
|
||||
except:
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
|
||||
@@ -1145,7 +1144,7 @@ class MMDiT(BaseModel):
|
||||
for k, v in model.items():
|
||||
if self.ignore_keys is not None:
|
||||
if (isinstance(self.ignore_keys, str) and re.match(self.ignore_keys, k)) or \
|
||||
(isinstance(self.ignore_keys, list) and k in self.ignore_keys):
|
||||
(isinstance(self.ignore_keys, list) and k in self.ignore_keys):
|
||||
ignore_ckpt[k] = v
|
||||
continue
|
||||
k = k.replace('model.diffusion_model.', '')
|
||||
@@ -1185,11 +1184,6 @@ class MMDiT(BaseModel):
|
||||
spatial_pos_embed = spatial_pos_embed[:, top:top + h, left:left + w, :]
|
||||
spatial_pos_embed = rearrange(spatial_pos_embed,
|
||||
'1 h w c -> 1 (h w) c')
|
||||
# print(spatial_pos_embed, top, left, h, w)
|
||||
# # t = get_2d_sincos_pos_embed_torch(self.hidden_size, w, h, 7.875, 7.875, device=device) #matches exactly for 1024 res
|
||||
# t = get_2d_sincos_pos_embed_torch(self.hidden_size, w, h, 7.5, 7.5, device=device) #scales better
|
||||
# # print(t)
|
||||
# return t
|
||||
return spatial_pos_embed
|
||||
|
||||
def unpatchify(self, x, hw=None):
|
||||
|
||||
@@ -1,2 +1,3 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from .pixart_alpha import PixArt
|
||||
|
||||
@@ -537,7 +537,7 @@ class FullAttention(nn.Module):
|
||||
k_img, k_txt = self.k_img_norm(k_img).view(
|
||||
b, -1, n * d), self.k_txt_norm(k_txt).view(b, -1, n * d)
|
||||
|
||||
### add position
|
||||
# add position
|
||||
q_img, k_img = apply_2d_rope(q_img, k_img, padded_pos_index, n, d)
|
||||
|
||||
# support varying length
|
||||
|
||||
@@ -9,6 +9,7 @@ import math
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from einops import rearrange
|
||||
|
||||
from scepter.modules.model.backbone.transformer.attention import drop_path
|
||||
|
||||
|
||||
@@ -299,3 +300,28 @@ class Mlp(nn.Module):
|
||||
x = self.fc2(x)
|
||||
x = self.drop(x)
|
||||
return x
|
||||
|
||||
|
||||
class T2IFinalLayer(nn.Module):
|
||||
"""
|
||||
The final layer of PixArt.
|
||||
"""
|
||||
def __init__(self, hidden_size, patch_size, out_channels):
|
||||
super().__init__()
|
||||
self.norm_final = nn.LayerNorm(hidden_size,
|
||||
elementwise_affine=False,
|
||||
eps=1e-6)
|
||||
self.linear = nn.Linear(hidden_size,
|
||||
patch_size * patch_size * out_channels,
|
||||
bias=True)
|
||||
self.scale_shift_table = nn.Parameter(
|
||||
torch.randn(2, hidden_size) / hidden_size**0.5)
|
||||
self.out_channels = out_channels
|
||||
|
||||
def forward(self, x, t):
|
||||
shift, scale = (self.scale_shift_table[None] + t[:, None]).chunk(2,
|
||||
dim=1)
|
||||
shift, scale = shift.squeeze(1), scale.squeeze(1)
|
||||
x = modulate(self.norm_final(x), shift, scale)
|
||||
x = self.linear(x)
|
||||
return x
|
||||
|
||||
@@ -8,8 +8,13 @@ from itertools import repeat as iter_repeat
|
||||
from typing import Iterable
|
||||
|
||||
import numpy as np
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
from einops import rearrange
|
||||
from torch import Tensor
|
||||
from torch.cuda import amp
|
||||
from torch.nn.utils.rnn import pad_sequence
|
||||
|
||||
|
||||
def _ntuple(n):
|
||||
@@ -127,3 +132,218 @@ def apply_2d_rope(xq,
|
||||
2) # point_wise mul, then flatten eg[[1,2],[3,4],[5,6]]->[1,2,3,4,5,6]
|
||||
xk_out = torch.view_as_real(xk_ * freqs_cis).flatten(2)
|
||||
return xq_out.type_as(xq), xk_out.type_as(xk)
|
||||
|
||||
|
||||
def sinusoidal_embedding_1d(dim, position):
|
||||
# preprocess
|
||||
assert dim % 2 == 0
|
||||
half = dim // 2
|
||||
position = position.type(torch.float64)
|
||||
|
||||
# calculation
|
||||
sinusoid = torch.outer(
|
||||
position, torch.pow(10000, -torch.arange(half).to(position).div(half)))
|
||||
x = torch.cat([torch.cos(sinusoid), torch.sin(sinusoid)], dim=1)
|
||||
return x.float()
|
||||
|
||||
|
||||
def frame_pad(x, seq_len, shapes):
|
||||
max_h, max_w = np.max(shapes, 0)
|
||||
frames = []
|
||||
cur_len = 0
|
||||
for h, w in shapes:
|
||||
frame_len = h * w
|
||||
frames.append(
|
||||
F.pad(
|
||||
x[cur_len:cur_len + frame_len].view(h, w, -1),
|
||||
(0, 0, 0, max_w - w, 0, max_h - h)) # .view(max_h * max_w, -1)
|
||||
)
|
||||
cur_len += frame_len
|
||||
if cur_len >= seq_len:
|
||||
break
|
||||
return torch.stack(frames)
|
||||
|
||||
|
||||
def frame_unpad(x, shapes):
|
||||
max_h, max_w = np.max(shapes, 0)
|
||||
x = rearrange(x, '(b h w) n c -> b h w n c', h=max_h, w=max_w)
|
||||
frames = []
|
||||
for i, (h, w) in enumerate(shapes):
|
||||
if i >= len(x):
|
||||
break
|
||||
frames.append(rearrange(x[i, :h, :w], 'h w n c -> (h w) n c'))
|
||||
return torch.concat(frames)
|
||||
|
||||
|
||||
@amp.autocast(enabled=False)
|
||||
def rope_params(max_seq_len, dim, theta=10000):
|
||||
"""
|
||||
Precompute the frequency tensor for complex exponentials.
|
||||
"""
|
||||
assert dim % 2 == 0
|
||||
freqs = torch.outer(
|
||||
torch.arange(max_seq_len),
|
||||
1.0 / torch.pow(theta,
|
||||
torch.arange(0, dim, 2).to(torch.float64).div(dim)))
|
||||
freqs = torch.polar(torch.ones_like(freqs), freqs)
|
||||
return freqs
|
||||
|
||||
|
||||
@amp.autocast(enabled=False)
|
||||
def rope_apply(x, grid_sizes, freqs):
|
||||
"""
|
||||
x: [B, L, N, C].
|
||||
grid_sizes: [B, 3].
|
||||
freqs: [M, C // 2].
|
||||
"""
|
||||
n, c = x.size(2), x.size(3) // 2
|
||||
|
||||
# split freqs
|
||||
freqs = freqs.split([c - 2 * (c // 3), c // 3, c // 3], dim=1)
|
||||
|
||||
# loop over samples
|
||||
output = []
|
||||
for i, (f, h, w) in enumerate(grid_sizes.tolist()):
|
||||
seq_len = f * h * w
|
||||
|
||||
# precompute multipliers
|
||||
x_i = torch.view_as_complex(x[i, :seq_len].to(torch.float64).reshape(
|
||||
seq_len, n, -1, 2))
|
||||
freqs_i = torch.cat([
|
||||
freqs[0][:f].view(f, 1, 1, -1).expand(f, h, w, -1),
|
||||
freqs[1][:h].view(1, h, 1, -1).expand(f, h, w, -1),
|
||||
freqs[2][:w].view(1, 1, w, -1).expand(f, h, w, -1)
|
||||
],
|
||||
dim=-1).reshape(seq_len, 1, -1)
|
||||
|
||||
# apply rotary embedding
|
||||
x_i = torch.view_as_real(x_i * freqs_i).flatten(2).type_as(x)
|
||||
x_i = torch.cat([x_i, x[i, seq_len:]])
|
||||
|
||||
# append to collection
|
||||
output.append(x_i)
|
||||
return torch.stack(output)
|
||||
|
||||
|
||||
@amp.autocast(enabled=False)
|
||||
def rope_apply_multires_pad(x, x_lens, x_shapes, freqs, pad=True):
|
||||
"""
|
||||
x: [B, L, N, C].
|
||||
x_lens: [B].
|
||||
x_shapes: [B, F, 2].
|
||||
freqs: [M, C // 2].
|
||||
"""
|
||||
n, c = x.size(2), x.size(3) // 2
|
||||
|
||||
# split freqs
|
||||
freqs = freqs.split([c - 2 * (c // 3), c // 3, c // 3], dim=1)
|
||||
|
||||
# loop over samples
|
||||
output = []
|
||||
for i, (seq_len,
|
||||
shapes) in enumerate(zip(x_lens.tolist(), x_shapes.tolist())):
|
||||
x_i = frame_pad(x[i], seq_len, shapes) # f, h, w, c
|
||||
f, h, w = x_i.shape[:3]
|
||||
pad_seq_len = f * h * w
|
||||
|
||||
# precompute multipliers
|
||||
x_i = torch.view_as_complex(
|
||||
x_i.to(torch.float64).reshape(pad_seq_len, n, -1, 2))
|
||||
freqs_i = torch.cat([
|
||||
freqs[0][:f].view(f, 1, 1, -1).expand(f, h, w, -1),
|
||||
freqs[1][:h].view(1, h, 1, -1).expand(f, h, w, -1),
|
||||
freqs[2][:w].view(1, 1, w, -1).expand(f, h, w, -1)
|
||||
],
|
||||
dim=-1).reshape(pad_seq_len, 1, -1)
|
||||
|
||||
# apply rotary embedding
|
||||
x_i = torch.view_as_real(x_i * freqs_i).flatten(2).type_as(x)
|
||||
x_i = frame_unpad(x_i, shapes)
|
||||
if pad:
|
||||
x_i = torch.cat([x_i, x[i, seq_len:]])
|
||||
|
||||
# append to collection
|
||||
output.append(x_i)
|
||||
return torch.stack(output) if pad else torch.concat(output)
|
||||
|
||||
|
||||
@amp.autocast(enabled=False)
|
||||
def rope_apply_multires(x, x_lens, x_shapes, freqs, pad=True):
|
||||
"""
|
||||
x: [B*L, N, C].
|
||||
x_lens: [B].
|
||||
x_shapes: [B, F, 2].
|
||||
freqs: [M, C // 2].
|
||||
"""
|
||||
n, c = x.size(1), x.size(2) // 2
|
||||
# split freqs
|
||||
freqs = freqs.split([c - 2 * (c // 3), c // 3, c // 3], dim=1)
|
||||
# loop over samples
|
||||
output = []
|
||||
st = 0
|
||||
for i, (seq_len,
|
||||
shapes) in enumerate(zip(x_lens.tolist(), x_shapes.tolist())):
|
||||
x_i = frame_pad(x[st:st + seq_len], seq_len, shapes) # f, h, w, c
|
||||
f, h, w = x_i.shape[:3]
|
||||
pad_seq_len = f * h * w
|
||||
# precompute multipliers
|
||||
x_i = torch.view_as_complex(
|
||||
x_i.to(torch.float64).reshape(pad_seq_len, n, -1, 2))
|
||||
freqs_i = torch.cat([
|
||||
freqs[0][:f].view(f, 1, 1, -1).expand(f, h, w, -1),
|
||||
freqs[1][:h].view(1, h, 1, -1).expand(f, h, w, -1),
|
||||
freqs[2][:w].view(1, 1, w, -1).expand(f, h, w, -1)
|
||||
],
|
||||
dim=-1).reshape(pad_seq_len, 1, -1)
|
||||
# apply rotary embedding
|
||||
x_i = torch.view_as_real(x_i * freqs_i).flatten(2).type_as(x)
|
||||
x_i = frame_unpad(x_i, shapes)
|
||||
# append to collection
|
||||
output.append(x_i)
|
||||
st += seq_len
|
||||
return pad_sequence(output) if pad else torch.concat(output)
|
||||
|
||||
|
||||
def rope(pos: Tensor, dim: int, theta: int) -> Tensor:
|
||||
assert dim % 2 == 0
|
||||
scale = torch.arange(0, dim, 2, dtype=torch.float64,
|
||||
device=pos.device) / dim
|
||||
omega = 1.0 / (theta**scale)
|
||||
out = torch.einsum('...n,d->...nd', pos, omega)
|
||||
out = torch.stack(
|
||||
[torch.cos(out), -torch.sin(out),
|
||||
torch.sin(out),
|
||||
torch.cos(out)],
|
||||
dim=-1)
|
||||
out = rearrange(out, 'b n d (i j) -> b n d i j', i=2, j=2)
|
||||
return out.float()
|
||||
|
||||
|
||||
def apply_rope(xq: Tensor, xk: Tensor,
|
||||
freqs_cis: Tensor) -> tuple[Tensor, Tensor]:
|
||||
xq_ = xq.float().reshape(*xq.shape[:-1], -1, 1, 2)
|
||||
xk_ = xk.float().reshape(*xk.shape[:-1], -1, 1, 2)
|
||||
xq_out = freqs_cis[..., 0] * xq_[..., 0] + freqs_cis[..., 1] * xq_[..., 1]
|
||||
xk_out = freqs_cis[..., 0] * xk_[..., 0] + freqs_cis[..., 1] * xk_[..., 1]
|
||||
return xq_out.reshape(*xq.shape).type_as(xq), xk_out.reshape(
|
||||
*xk.shape).type_as(xk)
|
||||
|
||||
|
||||
class EmbedND(nn.Module):
|
||||
def __init__(self, dim: int, theta: int, axes_dim: list[int]):
|
||||
super().__init__()
|
||||
self.dim = dim
|
||||
self.theta = theta
|
||||
self.axes_dim = axes_dim
|
||||
|
||||
def forward(self, ids: Tensor) -> Tensor:
|
||||
n_axes = ids.shape[-1]
|
||||
emb = torch.cat(
|
||||
[
|
||||
rope(ids[..., i], self.axes_dim[i], self.theta)
|
||||
for i in range(n_axes)
|
||||
],
|
||||
dim=-3,
|
||||
)
|
||||
|
||||
return emb.unsqueeze(1)
|
||||
|
||||
@@ -1,3 +1,7 @@
|
||||
from .samplers import BaseDiffusionSampler, FlowEluerSampler, DDIMSampler
|
||||
from .schedules import BaseNoiseScheduler, ScaledLinearScheduler, FlowMatchShiftScheduler
|
||||
from .diffusions import BaseDiffusion, DiffusionFluxRF
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
|
||||
from .diffusions import BaseDiffusion, DiffusionFluxRF
|
||||
from .samplers import BaseDiffusionSampler, DDIMSampler, FlowEluerSampler
|
||||
from .schedules import (BaseNoiseScheduler, FlowMatchShiftScheduler,
|
||||
ScaledLinearScheduler)
|
||||
|
||||
@@ -1,28 +1,35 @@
|
||||
import os
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import math
|
||||
import torch
|
||||
import os
|
||||
from collections import OrderedDict
|
||||
|
||||
from scepter.modules.utils.config import dict_to_yaml, Config
|
||||
import torch
|
||||
from tqdm import trange
|
||||
|
||||
from scepter.modules.model.registry import (DIFFUSION_SAMPLERS, DIFFUSIONS,
|
||||
NOISE_SCHEDULERS)
|
||||
from scepter.modules.utils.config import Config, dict_to_yaml
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
from scepter.modules.model.registry import DIFFUSIONS, NOISE_SCHEDULERS, DIFFUSION_SAMPLERS
|
||||
from tqdm import trange
|
||||
|
||||
|
||||
@DIFFUSIONS.register_class()
|
||||
class BaseDiffusion(object):
|
||||
para_dict = {
|
||||
"NOISE_SCHEDULER": {},
|
||||
"SAMPLER_SCHEDULER": {},
|
||||
"MIN_SNR_GAMMA": {
|
||||
"value": None,
|
||||
"description": "The minimum SNR gamma value for the loss function."
|
||||
'NOISE_SCHEDULER': {},
|
||||
'SAMPLER_SCHEDULER': {},
|
||||
'MIN_SNR_GAMMA': {
|
||||
'value': None,
|
||||
'description': 'The minimum SNR gamma value for the loss function.'
|
||||
},
|
||||
"PREDICTION_TYPE": {
|
||||
"value": "eps",
|
||||
"description": "The type of prediction to use for the loss function."
|
||||
'PREDICTION_TYPE': {
|
||||
'value': 'eps',
|
||||
'description':
|
||||
'The type of prediction to use for the loss function.'
|
||||
}
|
||||
}
|
||||
|
||||
def __init__(self, cfg, logger=None):
|
||||
super(BaseDiffusion, self).__init__()
|
||||
self.logger = logger
|
||||
@@ -30,23 +37,37 @@ class BaseDiffusion(object):
|
||||
self.init_params()
|
||||
|
||||
def init_params(self):
|
||||
self.min_snr_gamma = self.cfg.get("MIN_SNR_GAMMA", None)
|
||||
self.prediction_type = self.cfg.get("PREDICTION_TYPE", "eps")
|
||||
self.noise_scheduler = NOISE_SCHEDULERS.build(self.cfg.NOISE_SCHEDULER, logger=self.logger)
|
||||
self.sampler_scheduler = NOISE_SCHEDULERS.build(self.cfg.get("SAMPLER_SCHEDULER", self.cfg.NOISE_SCHEDULER),
|
||||
self.min_snr_gamma = self.cfg.get('MIN_SNR_GAMMA', None)
|
||||
self.prediction_type = self.cfg.get('PREDICTION_TYPE', 'eps')
|
||||
self.noise_scheduler = NOISE_SCHEDULERS.build(self.cfg.NOISE_SCHEDULER,
|
||||
logger=self.logger)
|
||||
self.sampler_scheduler = NOISE_SCHEDULERS.build(self.cfg.get(
|
||||
'SAMPLER_SCHEDULER', self.cfg.NOISE_SCHEDULER),
|
||||
logger=self.logger)
|
||||
self.num_timesteps = self.noise_scheduler.num_timesteps
|
||||
if self.cfg.have("WORK_DIR") and we.rank == 0:
|
||||
schedule_visualization = os.path.join(self.cfg.WORK_DIR, "noise_schedule.png")
|
||||
if self.cfg.have('WORK_DIR') and we.rank == 0:
|
||||
schedule_visualization = os.path.join(self.cfg.WORK_DIR,
|
||||
'noise_schedule.png')
|
||||
with FS.put_to(schedule_visualization) as local_path:
|
||||
self.noise_scheduler.plot_noise_sampling_map(local_path)
|
||||
schedule_visualization = os.path.join(self.cfg.WORK_DIR, "sampler_schedule.png")
|
||||
schedule_visualization = os.path.join(self.cfg.WORK_DIR,
|
||||
'sampler_schedule.png')
|
||||
with FS.put_to(schedule_visualization) as local_path:
|
||||
self.sampler_scheduler.plot_noise_sampling_map(local_path)
|
||||
|
||||
|
||||
def sample(self, noise, model, model_kwargs={}, steps=20, sampler=None, use_dynamic_cfg=False, guide_scale=None, guide_rescale=None,
|
||||
show_progress=False, return_intermediate=None, intermediate_callback=None, **kwargs):
|
||||
def sample(self,
|
||||
noise,
|
||||
model,
|
||||
model_kwargs={},
|
||||
steps=20,
|
||||
sampler=None,
|
||||
use_dynamic_cfg=False,
|
||||
guide_scale=None,
|
||||
guide_rescale=None,
|
||||
show_progress=False,
|
||||
return_intermediate=None,
|
||||
intermediate_callback=None,
|
||||
**kwargs):
|
||||
assert isinstance(steps, (int, torch.LongTensor))
|
||||
assert return_intermediate in (None, 'x0', 'xt')
|
||||
assert isinstance(sampler, (str, dict, Config))
|
||||
@@ -62,7 +83,9 @@ class BaseDiffusion(object):
|
||||
out = model(x=x_t, t=t, **model_kwargs)
|
||||
else:
|
||||
if use_dynamic_cfg:
|
||||
guidance_scale = 1 + guide_scale * ((1 - math.cos(math.pi * ((steps - timestamp.item()) / steps) ** 5.0)) / 2)
|
||||
guidance_scale = 1 + guide_scale * (
|
||||
(1 - math.cos(math.pi * (
|
||||
(steps - timestamp.item()) / steps)**5.0)) / 2)
|
||||
else:
|
||||
guidance_scale = guide_scale
|
||||
y_out = model(x=x_t, t=t, **model_kwargs[0])
|
||||
@@ -97,8 +120,7 @@ class BaseDiffusion(object):
|
||||
steps=steps,
|
||||
prediction_type=self.prediction_type,
|
||||
scheduler_ins=self.sampler_scheduler,
|
||||
callback_fn=callback_fn
|
||||
)
|
||||
callback_fn=callback_fn)
|
||||
|
||||
for _ in trange(steps, disable=not show_progress):
|
||||
trange.desc = sampler_output.msg
|
||||
@@ -109,14 +131,20 @@ class BaseDiffusion(object):
|
||||
intermediates.append(sampler_output.x_t)
|
||||
if intermediate_callback is not None:
|
||||
intermediate_callback(intermediates[-1])
|
||||
return (sampler_output.x_0, intermediates) if return_intermediate is not None else sampler_output.x_0
|
||||
return (sampler_output.x_0, intermediates
|
||||
) if return_intermediate is not None else sampler_output.x_0
|
||||
|
||||
|
||||
def loss(self, x_0, model, model_kwargs={}, reduction='mean', noise=None, **kwargs):
|
||||
def loss(self,
|
||||
x_0,
|
||||
model,
|
||||
model_kwargs={},
|
||||
reduction='mean',
|
||||
noise=None,
|
||||
**kwargs):
|
||||
# use noise scheduler to add noise
|
||||
if noise is None:
|
||||
noise = torch.randn_like(x_0)
|
||||
schedule_output = self.noise_scheduler.add_noise(x_0, noise)
|
||||
schedule_output = self.noise_scheduler.add_noise(x_0, noise, **kwargs)
|
||||
x_t, t, sigma, alpha = schedule_output.x_t, schedule_output.t, schedule_output.sigma, schedule_output.alpha
|
||||
out = model(x=x_t, t=t, **model_kwargs)
|
||||
|
||||
@@ -147,15 +175,23 @@ class BaseDiffusion(object):
|
||||
if isinstance(sampler, str):
|
||||
if sampler not in DIFFUSION_SAMPLERS.class_map:
|
||||
if self.logger is not None:
|
||||
self.logger.info(f"{sampler} not in the defined samplers list {DIFFUSION_SAMPLERS.class_map.keys()}")
|
||||
self.logger.info(
|
||||
f'{sampler} not in the defined samplers list {DIFFUSION_SAMPLERS.class_map.keys()}'
|
||||
)
|
||||
else:
|
||||
print(f"{sampler} not in the defined samplers list {DIFFUSION_SAMPLERS.class_map.keys()}")
|
||||
print(
|
||||
f'{sampler} not in the defined samplers list {DIFFUSION_SAMPLERS.class_map.keys()}'
|
||||
)
|
||||
return None
|
||||
sampler_cfg = Config(cfg_dict={"NAME": sampler}, load=False)
|
||||
sampler_ins = DIFFUSION_SAMPLERS.build(sampler_cfg, logger=self.logger)
|
||||
sampler_cfg = Config(cfg_dict={'NAME': sampler}, load=False)
|
||||
sampler_ins = DIFFUSION_SAMPLERS.build(sampler_cfg,
|
||||
logger=self.logger)
|
||||
elif isinstance(sampler, (Config, dict, OrderedDict)):
|
||||
if isinstance(sampler, (dict, OrderedDict)):
|
||||
sampler = Config(cfg_dict={k.upper():v for k, v in dict(sampler).items()}, load=False)
|
||||
sampler = Config(
|
||||
cfg_dict={k.upper(): v
|
||||
for k, v in dict(sampler).items()},
|
||||
load=False)
|
||||
sampler_ins = DIFFUSION_SAMPLERS.build(sampler, logger=self.logger)
|
||||
else:
|
||||
raise NotImplementedError
|
||||
@@ -171,36 +207,45 @@ class BaseDiffusion(object):
|
||||
BaseDiffusion.para_dict,
|
||||
set_name=True)
|
||||
|
||||
|
||||
@DIFFUSIONS.register_class()
|
||||
class DiffusionFluxRF(BaseDiffusion):
|
||||
para_dict = {
|
||||
"PREDICTION_TYPE": {
|
||||
"value": "raw",
|
||||
"description": "The type of prediction to use for the loss function."
|
||||
'PREDICTION_TYPE': {
|
||||
'value': 'raw',
|
||||
'description':
|
||||
'The type of prediction to use for the loss function.'
|
||||
}
|
||||
}
|
||||
para_dict.update(BaseDiffusion.para_dict)
|
||||
|
||||
def __init__(self, cfg, logger=None):
|
||||
super(DiffusionFluxRF, self).__init__(cfg, logger=logger)
|
||||
self.prediction_type = self.cfg.get("PREDICTION_TYPE", "raw")
|
||||
self.prediction_type = self.cfg.get('PREDICTION_TYPE', 'raw')
|
||||
|
||||
def loss(self, x_0, model, model_kwargs={}, reduction='mean', noise=None, **kwargs):
|
||||
def loss(self,
|
||||
x_0,
|
||||
model,
|
||||
model_kwargs={},
|
||||
reduction='mean',
|
||||
noise=None,
|
||||
**kwargs):
|
||||
if noise is None:
|
||||
noise = torch.randn_like(x_0)
|
||||
schedule_output = self.noise_scheduler.add_noise(x_0, noise)
|
||||
schedule_output = self.noise_scheduler.add_noise(x_0, noise, **kwargs)
|
||||
x_t, t, sigma = schedule_output.x_t, schedule_output.t, schedule_output.sigma
|
||||
out = model(x=x_t, t=sigma, **model_kwargs)
|
||||
# raw
|
||||
if self.prediction_type == "raw":
|
||||
if self.prediction_type == 'raw':
|
||||
target = noise - x_0
|
||||
out = out
|
||||
elif self.prediction_type == "sigma_scaled":
|
||||
elif self.prediction_type == 'sigma_scaled':
|
||||
target = x_0
|
||||
out = out * (-sigma) + x_t
|
||||
else:
|
||||
raise NotImplementedError
|
||||
|
||||
loss = (target - out) ** 2
|
||||
loss = (target - out)**2
|
||||
if reduction == 'mean':
|
||||
loss = loss.flatten(1).mean(dim=1)
|
||||
|
||||
@@ -222,7 +267,7 @@ class DiffusionFluxRF(BaseDiffusion):
|
||||
model,
|
||||
model_kwargs={},
|
||||
steps=20,
|
||||
sampler = None,
|
||||
sampler=None,
|
||||
show_progress=False,
|
||||
return_intermediate=None,
|
||||
intermediate_callback=None,
|
||||
@@ -233,9 +278,12 @@ class DiffusionFluxRF(BaseDiffusion):
|
||||
assert isinstance(sampler, (str, dict, Config))
|
||||
intermediates = []
|
||||
|
||||
def callback_fn(x_t, t, sigma):
|
||||
sigma = torch.full((x_t.shape[0],), sigma, dtype=x_t.dtype, device=x_t.device)
|
||||
x_0 = model(x = x_t, t=sigma, **model_kwargs)
|
||||
def callback_fn(x_t, t, sigma=None, alpha=None):
|
||||
sigma = torch.full((x_t.shape[0], ),
|
||||
sigma,
|
||||
dtype=x_t.dtype,
|
||||
device=x_t.device)
|
||||
x_0 = model(x=x_t, t=sigma, **model_kwargs)
|
||||
return x_0
|
||||
|
||||
sampler_ins = self.get_sampler(sampler)
|
||||
@@ -243,11 +291,10 @@ class DiffusionFluxRF(BaseDiffusion):
|
||||
# this is ignored for schnell
|
||||
sampler_output = sampler_ins.preprare_sampler(
|
||||
noise,
|
||||
steps = steps,
|
||||
steps=steps,
|
||||
prediction_type=self.prediction_type,
|
||||
scheduler_ins = self.sampler_scheduler,
|
||||
callback_fn=callback_fn
|
||||
)
|
||||
scheduler_ins=self.sampler_scheduler,
|
||||
callback_fn=callback_fn)
|
||||
|
||||
for _ in trange(steps, disable=not show_progress):
|
||||
trange.desc = sampler_output.msg
|
||||
@@ -258,11 +305,12 @@ class DiffusionFluxRF(BaseDiffusion):
|
||||
intermediates.append(sampler_output.x_t)
|
||||
if intermediate_callback is not None:
|
||||
intermediate_callback(intermediates[-1])
|
||||
return (sampler_output.x_0, intermediates) if return_intermediate is not None else sampler_output.x_t
|
||||
return (sampler_output.x_0, intermediates
|
||||
) if return_intermediate is not None else sampler_output.x_t
|
||||
|
||||
@staticmethod
|
||||
def get_config_template():
|
||||
return dict_to_yaml('DIFFUSIONS',
|
||||
__class__.__name__,
|
||||
DiffusionFluxRF.para_dict,
|
||||
set_name=True)
|
||||
set_name=True)
|
||||
|
||||
@@ -1,9 +1,15 @@
|
||||
from dataclasses import dataclass, field
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from dataclasses import dataclass
|
||||
|
||||
import torch
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
|
||||
from scepter.modules.model.registry import DIFFUSION_SAMPLERS
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
|
||||
from .util import _i
|
||||
|
||||
|
||||
@dataclass
|
||||
class SamplerOutput(object):
|
||||
callback_fn: callable
|
||||
@@ -24,9 +30,10 @@ class SamplerOutput(object):
|
||||
self.__setattr__(key, value)
|
||||
|
||||
|
||||
@DIFFUSION_SAMPLERS.register_class("base")
|
||||
@DIFFUSION_SAMPLERS.register_class('base')
|
||||
class BaseDiffusionSampler(object):
|
||||
para_dict = {}
|
||||
|
||||
def __init__(self, cfg, logger=None):
|
||||
super(BaseDiffusionSampler, self).__init__()
|
||||
self.logger = logger
|
||||
@@ -34,11 +41,13 @@ class BaseDiffusionSampler(object):
|
||||
self.init_params()
|
||||
|
||||
def init_params(self):
|
||||
self.discretization_type = self.cfg.get("DISCRETIZATION_TYPE", "linspace")
|
||||
self.discard_penultimate_step = self.cfg.get("DISCARD_PENULTIMATE_STEP", False)
|
||||
self.free_steps = self.cfg.get("FREE_STEPS", None)
|
||||
self.t_max = self.cfg.get("T_MAX", None)
|
||||
self.t_min = self.cfg.get("T_MIN", None)
|
||||
self.discretization_type = self.cfg.get('DISCRETIZATION_TYPE',
|
||||
'linspace')
|
||||
self.discard_penultimate_step = self.cfg.get(
|
||||
'DISCARD_PENULTIMATE_STEP', False)
|
||||
self.free_steps = self.cfg.get('FREE_STEPS', None)
|
||||
self.t_max = self.cfg.get('T_MAX', None)
|
||||
self.t_min = self.cfg.get('T_MIN', None)
|
||||
|
||||
def discretization(self, steps=20, num_timesteps=1000, **kwargs):
|
||||
# get timesteps
|
||||
@@ -60,15 +69,23 @@ class BaseDiffusionSampler(object):
|
||||
steps = torch.tensor(self.free_steps)
|
||||
else:
|
||||
raise NotImplementedError(
|
||||
f'{self.discretization_type} discretization not implemented')
|
||||
f'{self.discretization_type} discretization not implemented'
|
||||
)
|
||||
steps = steps.clamp_(t_min, t_max)
|
||||
elif isinstance(steps, list):
|
||||
steps = torch.tensor(steps)
|
||||
timesteps = torch.as_tensor(steps, dtype=torch.float32)
|
||||
return timesteps
|
||||
|
||||
def preprare_sampler(self, noise, steps=20, scheduler_ins=None, prediction_type="",
|
||||
sigmas=None, betas=None, alphas=None, callback_fn = None,
|
||||
def preprare_sampler(self,
|
||||
noise,
|
||||
steps=20,
|
||||
scheduler_ins=None,
|
||||
prediction_type='',
|
||||
sigmas=None,
|
||||
betas=None,
|
||||
alphas=None,
|
||||
callback_fn=None,
|
||||
**kwargs):
|
||||
'''
|
||||
1. Control the model's inputs and outputs externally in the solver by callback_fn,
|
||||
@@ -80,33 +97,40 @@ class BaseDiffusionSampler(object):
|
||||
which manage all necessary information.
|
||||
'''
|
||||
num_timesteps = scheduler_ins.num_timesteps if scheduler_ins is not None else 1000
|
||||
timestamps = self.discretization(steps, num_timesteps=num_timesteps, **kwargs)
|
||||
alphas = scheduler_ins.t_to_alpha(timestamps, **kwargs) if scheduler_ins is not None else alphas
|
||||
betas = scheduler_ins.t_to_beta(timestamps, **kwargs) if scheduler_ins is not None else betas
|
||||
sigmas = scheduler_ins.t_to_sigma(timestamps, **kwargs) if scheduler_ins is not None else sigmas
|
||||
alphas_init = scheduler_ins.t_to_alpha_init(timestamps, **kwargs) if scheduler_ins is not None else alphas
|
||||
betas_init = scheduler_ins.t_to_beta_init(timestamps, **kwargs) if scheduler_ins is not None else betas
|
||||
sigmas_init = scheduler_ins.t_to_sigma_init(timestamps, **kwargs) if scheduler_ins is not None else sigmas
|
||||
timestamps = self.discretization(steps,
|
||||
num_timesteps=num_timesteps,
|
||||
**kwargs)
|
||||
alphas = scheduler_ins.t_to_alpha(
|
||||
timestamps, **kwargs) if scheduler_ins is not None else alphas
|
||||
betas = scheduler_ins.t_to_beta(
|
||||
timestamps, **kwargs) if scheduler_ins is not None else betas
|
||||
sigmas = scheduler_ins.t_to_sigma(
|
||||
timestamps, **kwargs) if scheduler_ins is not None else sigmas
|
||||
alphas_init = scheduler_ins.t_to_alpha_init(
|
||||
timestamps, **kwargs) if scheduler_ins is not None else alphas
|
||||
betas_init = scheduler_ins.t_to_beta_init(
|
||||
timestamps, **kwargs) if scheduler_ins is not None else betas
|
||||
sigmas_init = scheduler_ins.t_to_sigma_init(
|
||||
timestamps, **kwargs) if scheduler_ins is not None else sigmas
|
||||
|
||||
output = SamplerOutput(
|
||||
callback_fn=callback_fn,
|
||||
prediction_type=prediction_type,
|
||||
alphas=alphas,
|
||||
betas=betas,
|
||||
sigmas=sigmas,
|
||||
alphas_init=alphas_init,
|
||||
betas_init=betas_init,
|
||||
sigmas_init=sigmas_init,
|
||||
ts=timestamps,
|
||||
x_t=noise,
|
||||
x_0=noise,
|
||||
step=0,
|
||||
msg=f"step 0"
|
||||
)
|
||||
output = SamplerOutput(callback_fn=callback_fn,
|
||||
prediction_type=prediction_type,
|
||||
alphas=alphas,
|
||||
betas=betas,
|
||||
sigmas=sigmas,
|
||||
alphas_init=alphas_init,
|
||||
betas_init=betas_init,
|
||||
sigmas_init=sigmas_init,
|
||||
ts=timestamps,
|
||||
x_t=noise,
|
||||
x_0=noise,
|
||||
step=0,
|
||||
msg='step 0')
|
||||
return output
|
||||
|
||||
def step(self, sampler_ouput):
|
||||
raise NotImplementedError(f'DiffusionSampler step function not implemented')
|
||||
raise NotImplementedError(
|
||||
'DiffusionSampler step function not implemented')
|
||||
|
||||
def __repr__(self) -> str:
|
||||
return f'{self.__class__.__name__}' + ' ' + super().__repr__()
|
||||
@@ -119,24 +143,33 @@ class BaseDiffusionSampler(object):
|
||||
set_name=True)
|
||||
|
||||
|
||||
@DIFFUSION_SAMPLERS.register_class("eluer")
|
||||
@DIFFUSION_SAMPLERS.register_class('eluer')
|
||||
class EulerSampler(BaseDiffusionSampler):
|
||||
def step(self, sampler_ouput):
|
||||
pass
|
||||
|
||||
|
||||
@DIFFUSION_SAMPLERS.register_class("ddim")
|
||||
@DIFFUSION_SAMPLERS.register_class('ddim')
|
||||
class DDIMSampler(BaseDiffusionSampler):
|
||||
|
||||
def init_params(self):
|
||||
super().init_params()
|
||||
self.eta = self.cfg.get('ETA', 0.)
|
||||
self.discretization_type = self.cfg.get("DISCRETIZATION_TYPE", "trailing")
|
||||
self.discretization_type = self.cfg.get('DISCRETIZATION_TYPE',
|
||||
'trailing')
|
||||
|
||||
def preprare_sampler(self, noise, steps=20, scheduler_ins=None, prediction_type="",
|
||||
sigmas=None, betas=None, alphas=None, callback_fn = None,
|
||||
def preprare_sampler(self,
|
||||
noise,
|
||||
steps=20,
|
||||
scheduler_ins=None,
|
||||
prediction_type='',
|
||||
sigmas=None,
|
||||
betas=None,
|
||||
alphas=None,
|
||||
callback_fn=None,
|
||||
**kwargs):
|
||||
output = super().preprare_sampler(noise, steps, scheduler_ins, prediction_type, sigmas, betas, alphas, callback_fn, **kwargs)
|
||||
output = super().preprare_sampler(noise, steps, scheduler_ins,
|
||||
prediction_type, sigmas, betas,
|
||||
alphas, callback_fn, **kwargs)
|
||||
sigmas = output.sigmas
|
||||
sigmas = torch.cat([sigmas, sigmas.new_zeros([1])])
|
||||
sigmas_vp = (sigmas**2 / (1 + sigmas**2))**0.5
|
||||
@@ -153,42 +186,52 @@ class DDIMSampler(BaseDiffusionSampler):
|
||||
sigma_init = _i(sampler_output.sigmas_init, step, x_t[:1])
|
||||
|
||||
x = sampler_output.callback_fn(x_t, t, sigma_init, alpha_init)
|
||||
noise_factor = self.eta * (sigmas_vp[step + 1] ** 2 / sigmas_vp[step] ** 2 *
|
||||
(1 - (1 - sigmas_vp[step] ** 2) /
|
||||
(1 - sigmas_vp[step + 1] ** 2)))
|
||||
d = (x_t - (1 - sigmas_vp[step] ** 2) ** 0.5 * x) / sigmas_vp[step]
|
||||
noise_factor = self.eta * (sigmas_vp[step + 1]**2 /
|
||||
sigmas_vp[step]**2 *
|
||||
(1 - (1 - sigmas_vp[step]**2) /
|
||||
(1 - sigmas_vp[step + 1]**2)))
|
||||
d = (x_t - (1 - sigmas_vp[step]**2)**0.5 * x) / sigmas_vp[step]
|
||||
x = (1 - sigmas_vp[step + 1] ** 2) ** 0.5 * x + \
|
||||
(sigmas_vp[step + 1] ** 2 - noise_factor ** 2) ** 0.5 * d
|
||||
sampler_output.x_0 = x
|
||||
if sigmas_vp[step + 1] > 0:
|
||||
x += noise_factor * torch.randn_like(x)
|
||||
# print("i:", step, "sigma_init:", sigma_init, "alpha_init", alpha_init, "sigmas_vp[i]", sigmas_vp[step], "torch.sum(x_0):", torch.sum(x_0), "torch.sum(x):", torch.sum(x))
|
||||
sampler_output.x_t = x
|
||||
sampler_output.step += 1
|
||||
sampler_output.msg = f'step {step}'
|
||||
return sampler_output
|
||||
|
||||
|
||||
@DIFFUSION_SAMPLERS.register_class("flow_eluer")
|
||||
@DIFFUSION_SAMPLERS.register_class('flow_eluer')
|
||||
class FlowEluerSampler(BaseDiffusionSampler):
|
||||
def preprare_sampler(self, noise, steps=20, scheduler_ins=None, prediction_type="",
|
||||
sigmas=None, betas=None, alphas=None, callback_fn = None,
|
||||
def preprare_sampler(self,
|
||||
noise,
|
||||
steps=20,
|
||||
scheduler_ins=None,
|
||||
prediction_type='',
|
||||
sigmas=None,
|
||||
betas=None,
|
||||
alphas=None,
|
||||
callback_fn=None,
|
||||
**kwargs):
|
||||
if noise.ndim == 3:
|
||||
seq_len = noise.shape[2] // 4
|
||||
else:
|
||||
n, _, h, w = noise.shape
|
||||
seq_len = (h // 2 * w // 2)
|
||||
kwargs["seq_len"] = seq_len
|
||||
output = super().preprare_sampler(noise, steps, scheduler_ins, prediction_type, sigmas, betas, alphas, callback_fn, **kwargs)
|
||||
kwargs['seq_len'] = seq_len
|
||||
output = super().preprare_sampler(noise, steps, scheduler_ins,
|
||||
prediction_type, sigmas, betas,
|
||||
alphas, callback_fn, **kwargs)
|
||||
return output
|
||||
|
||||
def step(self, sampler_output):
|
||||
step = sampler_output.step
|
||||
x_t = sampler_output.x_t
|
||||
sigma_curr, sigma_prev = sampler_output.sigmas[step], sampler_output.sigmas[step + 1]
|
||||
sigma_curr, sigma_prev = sampler_output.sigmas[
|
||||
step], sampler_output.sigmas[step + 1]
|
||||
prediction_type = sampler_output.prediction_type
|
||||
assert prediction_type in ("raw", "sigma_scaled")
|
||||
assert prediction_type in ('raw', 'sigma_scaled')
|
||||
t = sampler_output.ts[step]
|
||||
x_0 = sampler_output.callback_fn(x_t, t, sigma_curr)
|
||||
x_t = x_t + (sigma_prev - sigma_curr) * x_0
|
||||
@@ -198,7 +241,7 @@ class FlowEluerSampler(BaseDiffusionSampler):
|
||||
sampler_output.msg = f'step {step}, sigma_curr: {sigma_curr}, sigma_prev: {sigma_prev}'
|
||||
return sampler_output
|
||||
|
||||
def discretization(self, steps=20, num_timesteps = 1000, **kwargs):
|
||||
def discretization(self, steps=20, num_timesteps=1000, **kwargs):
|
||||
# extra step for zero
|
||||
timesteps = torch.linspace(num_timesteps, 0, steps + 1)
|
||||
return timesteps
|
||||
@@ -208,4 +251,4 @@ class FlowEluerSampler(BaseDiffusionSampler):
|
||||
return dict_to_yaml('DIFFUSION_SAMPLERS',
|
||||
__class__.__name__,
|
||||
FlowEluerSampler.para_dict,
|
||||
set_name=True)
|
||||
set_name=True)
|
||||
|
||||
@@ -1,17 +1,20 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import math
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Callable
|
||||
|
||||
import torch
|
||||
import numpy as np
|
||||
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.utils.math_plot import plot_multi_curves
|
||||
from scepter.modules.model.registry import NOISE_SCHEDULERS
|
||||
import torch
|
||||
from torch import Tensor
|
||||
|
||||
from scepter.modules.model.registry import NOISE_SCHEDULERS
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.utils.math_plot import plot_multi_curves
|
||||
|
||||
from .util import _i
|
||||
|
||||
|
||||
@dataclass
|
||||
class ScheduleOutput(object):
|
||||
x_t: torch.Tensor
|
||||
@@ -27,69 +30,69 @@ class ScheduleOutput(object):
|
||||
|
||||
@NOISE_SCHEDULERS.register_class()
|
||||
class BaseNoiseScheduler(object):
|
||||
'''
|
||||
In the diffusion model, the parameters related to the noise schedule are alpha, beta,
|
||||
and sigma. The following are the definitions of the above three parameters, which should
|
||||
be the basic property for the instance of noise scheduler.
|
||||
\alpha_{t} = \sqrt{1 - \beta_{t}^2} \alpha is the strength of signal and \beta is the strength of noise
|
||||
\sigma_{t} = \sqrt{1 - \overline\alpha} = \sqrt{1 - \prod_{i=1}^{t}\alpha^2_{i}} (P(x_{t}|x_{0}) ~ N(\overline\alpha x_{0}, \sigma^2))
|
||||
|
||||
where sigma_{t} is the var of p(x_{t-1}|x_{t}, x_{0}).
|
||||
|
||||
(reference to https://arxiv.org/abs/2010.02502)
|
||||
let sigma transfer to beta:
|
||||
square_\beta = 1 - \frac{1 - square_\sigma_{t}}{1 - square_\sigma_{t - 1 }}
|
||||
|
||||
'''
|
||||
para_dict = {
|
||||
"NUM_TIMESTEPS": {
|
||||
"value": 1000,
|
||||
"description": "The number of timesteps for sampling."
|
||||
'NUM_TIMESTEPS': {
|
||||
'value': 1000,
|
||||
'description': 'The number of timesteps for sampling.'
|
||||
},
|
||||
}
|
||||
|
||||
def __init__(self, cfg, logger=None):
|
||||
super(BaseNoiseScheduler, self).__init__()
|
||||
self.logger = logger
|
||||
self.cfg = cfg
|
||||
self.init_params()
|
||||
self.get_schedule()
|
||||
# self.check_function()
|
||||
|
||||
def init_params(self):
|
||||
self.num_timesteps = self.cfg.get("NUM_TIMESTEPS", 1000)
|
||||
self._sample_steps = torch.arange(self.num_timesteps, dtype=torch.float32)
|
||||
self.num_timesteps = self.cfg.get('NUM_TIMESTEPS', 1000)
|
||||
self._sample_steps = torch.arange(self.num_timesteps,
|
||||
dtype=torch.float32)
|
||||
self._sigmas, self._betas, self._alphas, self._timesteps = None, None, None, None
|
||||
|
||||
def check_function(self):
|
||||
# for the same t, we should gurantee t_to_sigma and sigma_to_t is aligned
|
||||
try:
|
||||
predict_timestamps = self.sigma_to_t(self.sigmas)
|
||||
predict_sigmas = self.t_to_sigma(self._timesteps)
|
||||
diff_sigmas = torch.sum(torch.abs(predict_sigmas - self.sigmas))
|
||||
diff_timestamps = torch.sum(torch.abs(predict_timestamps - self._timesteps))
|
||||
diff_timestamps = torch.sum(
|
||||
torch.abs(predict_timestamps - self._timesteps))
|
||||
if diff_sigmas > 1e-3 or diff_timestamps > 1:
|
||||
self.logger.info(f"The noise scheduler {self.__class__.__name__} is not correct, "
|
||||
f"please check the function sigma_to_t or t_to_sigma."
|
||||
f"Info: diff sigmas {diff_sigmas}, diff timestamps {diff_timestamps}")
|
||||
raise "The noise scheduler checked failed."
|
||||
self.logger.info(
|
||||
f'The noise scheduler {self.__class__.__name__} is not correct, '
|
||||
f'please check the function sigma_to_t or t_to_sigma.'
|
||||
f'Info: diff sigmas {diff_sigmas}, diff timestamps {diff_timestamps}'
|
||||
)
|
||||
raise 'The noise scheduler checked failed.'
|
||||
else:
|
||||
self.logger.info(f"The noise scheduler {self.__class__.__name__} is checked and passed.")
|
||||
self.logger.info(
|
||||
f'The noise scheduler {self.__class__.__name__} is checked and passed.'
|
||||
)
|
||||
except Exception as e:
|
||||
if isinstance(e, NotImplementedError):
|
||||
self.logger.info("Not implemented function sigma_to_t or t_to_sigma, skip check.")
|
||||
self.logger.info(
|
||||
'Not implemented function sigma_to_t or t_to_sigma, skip check.'
|
||||
)
|
||||
else:
|
||||
self.logger.info(f"The noise scheduler {self.__class__.__name__} is not correct, "
|
||||
f"please check the function sigma_to_t or t_to_sigma. Error: {e}")
|
||||
self.logger.info(
|
||||
f'The noise scheduler {self.__class__.__name__} is not correct, '
|
||||
f'please check the function sigma_to_t or t_to_sigma. Error: {e}'
|
||||
)
|
||||
raise e
|
||||
|
||||
def get_schedule(self):
|
||||
raise NotImplementedError(f'NoiseScheduler get_schedule function not implemented')
|
||||
raise NotImplementedError(
|
||||
'NoiseScheduler get_schedule function not implemented')
|
||||
|
||||
def square_betas_to_sigmas(self, square_betas):
|
||||
return torch.sqrt(1 - torch.cumprod(1 - square_betas, dim=0))
|
||||
|
||||
def sigmas_to_square_betas(self, sigmas):
|
||||
square_alphas = 1 - sigmas ** 2
|
||||
betas = 1 - torch.cat([square_alphas[:1], square_alphas[1:] / square_alphas[:-1]])
|
||||
square_alphas = 1 - sigmas**2
|
||||
betas = 1 - torch.cat(
|
||||
[square_alphas[:1], square_alphas[1:] / square_alphas[:-1]])
|
||||
return betas
|
||||
|
||||
def sigma_to_t(self, sigma, **kwargs):
|
||||
if sigma == float('inf'):
|
||||
t = torch.full_like(sigma, len(self._sigmas) - 1)
|
||||
@@ -109,6 +112,7 @@ class BaseNoiseScheduler(object):
|
||||
if t.ndim == 0:
|
||||
t = t.unsqueeze(0)
|
||||
return t
|
||||
|
||||
def t_to_sigma(self, t, **kwargs):
|
||||
t = t.float()
|
||||
low_idx, high_idx, w = t.floor().long(), t.ceil().long(), t.frac()
|
||||
@@ -129,20 +133,23 @@ class BaseNoiseScheduler(object):
|
||||
square_beta = self.sigmas_to_square_betas(sigma)
|
||||
return torch.sqrt(square_beta)
|
||||
|
||||
def add_noise(self, x_0, noise = None, t = None):
|
||||
def add_noise(self, x_0, noise=None, t=None, **kwargs):
|
||||
if t is None:
|
||||
t = torch.randint(0, self.num_timesteps, (x_0.shape[0],), device=x_0.device).long()
|
||||
t = torch.randint(0,
|
||||
self.num_timesteps, (x_0.shape[0], ),
|
||||
device=x_0.device).long()
|
||||
alpha = _i(self.alphas, t, x_0)
|
||||
sigma = _i(self.sigmas, t, x_0)
|
||||
x_t = alpha * x_0 + sigma * noise
|
||||
|
||||
return ScheduleOutput(x_0 = x_0, x_t = x_t, t = t, alpha=alpha, sigma=sigma)
|
||||
return ScheduleOutput(x_0=x_0, x_t=x_t, t=t, alpha=alpha, sigma=sigma)
|
||||
|
||||
def t_to_alpha_init(self, t, **kwargs):
|
||||
indices = t.long()
|
||||
indices[indices >= self.num_timesteps] = self.num_timesteps - 1
|
||||
timesteps = self.timesteps.to(t)[indices]
|
||||
step_indices = [(self.timesteps.to(t) == t).nonzero().item() for t in timesteps]
|
||||
step_indices = [(self.timesteps.to(t) == t).nonzero().item()
|
||||
for t in timesteps]
|
||||
alpha = self.alphas[step_indices].flatten().to(t)
|
||||
return alpha
|
||||
|
||||
@@ -150,7 +157,8 @@ class BaseNoiseScheduler(object):
|
||||
indices = t.long()
|
||||
indices[indices >= self.num_timesteps] = self.num_timesteps - 1
|
||||
timesteps = self.timesteps.to(t)[indices]
|
||||
step_indices = [(self.timesteps.to(t) == t).nonzero().item() for t in timesteps]
|
||||
step_indices = [(self.timesteps.to(t) == t).nonzero().item()
|
||||
for t in timesteps]
|
||||
beta = self.betas[step_indices].flatten().to(t)
|
||||
return beta
|
||||
|
||||
@@ -158,7 +166,8 @@ class BaseNoiseScheduler(object):
|
||||
indices = t.long()
|
||||
indices[indices >= self.num_timesteps] = self.num_timesteps - 1
|
||||
timesteps = self.timesteps.to(t)[indices]
|
||||
step_indices = [(self.timesteps.to(t) == t).nonzero().item() for t in timesteps]
|
||||
step_indices = [(self.timesteps.to(t) == t).nonzero().item()
|
||||
for t in timesteps]
|
||||
sigma = self.sigmas[step_indices].flatten().to(t)
|
||||
return sigma
|
||||
|
||||
@@ -178,9 +187,10 @@ class BaseNoiseScheduler(object):
|
||||
# Shift so the last timestep is zero.
|
||||
alphas_bar_sqrt -= alphas_bar_sqrt_T
|
||||
# Scale so the first timestep is back to the old value.
|
||||
alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T)
|
||||
alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 -
|
||||
alphas_bar_sqrt_T)
|
||||
# Convert alphas_bar_sqrt to betas
|
||||
alphas_bar = alphas_bar_sqrt ** 2 # Revert sqrt
|
||||
alphas_bar = alphas_bar_sqrt**2 # Revert sqrt
|
||||
return alphas_bar
|
||||
|
||||
@property
|
||||
@@ -201,20 +211,26 @@ class BaseNoiseScheduler(object):
|
||||
|
||||
# plot the noise sampling map
|
||||
def plot_noise_sampling_map(self, save_path):
|
||||
y = [
|
||||
{"data": self._sigmas.cpu().numpy(), "label": "sigmas"},
|
||||
{"data": self._betas.cpu().numpy(), "label": "betas"},
|
||||
{"data": self._alphas.cpu().numpy(), "label": "alphas"},
|
||||
{"data": self._timesteps.cpu().numpy()/self.num_timesteps, "label": "timesteps"}
|
||||
]
|
||||
y = [{
|
||||
'data': self._sigmas.cpu().numpy(),
|
||||
'label': 'sigmas'
|
||||
}, {
|
||||
'data': self._betas.cpu().numpy(),
|
||||
'label': 'betas'
|
||||
}, {
|
||||
'data': self._alphas.cpu().numpy(),
|
||||
'label': 'alphas'
|
||||
}, {
|
||||
'data': self._timesteps.cpu().numpy() / self.num_timesteps,
|
||||
'label': 'timesteps'
|
||||
}]
|
||||
plot_multi_curves(
|
||||
x=self._sample_steps.cpu().numpy(),
|
||||
y=y,
|
||||
x_label='timesteps',
|
||||
y_label=None,
|
||||
title=f"{self.__class__.__name__}'s noise sampling map",
|
||||
save_path=save_path
|
||||
)
|
||||
save_path=save_path)
|
||||
return save_path
|
||||
|
||||
def __repr__(self) -> str:
|
||||
@@ -231,18 +247,24 @@ class BaseNoiseScheduler(object):
|
||||
@NOISE_SCHEDULERS.register_class()
|
||||
class ScaledLinearScheduler(BaseNoiseScheduler):
|
||||
para_dict = {}
|
||||
|
||||
def init_params(self):
|
||||
super().init_params()
|
||||
self.beta_min = self.cfg.get('BETA_MIN', 0.00085)
|
||||
self.beta_max = self.cfg.get('BETA_MAX', 0.012)
|
||||
self.snr_shift_scale = self.cfg.get('SNR_SHIFT_SCALE', None)
|
||||
self.rescale_betas_zero_snr = self.cfg.get('RESCALE_BETAS_ZERO_SNR', False)
|
||||
self.rescale_betas_zero_snr = self.cfg.get('RESCALE_BETAS_ZERO_SNR',
|
||||
False)
|
||||
|
||||
def square_betas_to_sigmas(self, square_betas, snr_shift_scale=None, rescale_betas_zero_snr=False):
|
||||
def square_betas_to_sigmas(self,
|
||||
square_betas,
|
||||
snr_shift_scale=None,
|
||||
rescale_betas_zero_snr=False):
|
||||
if snr_shift_scale is not None or rescale_betas_zero_snr:
|
||||
alphas_cumprod = torch.cumprod(1 - square_betas, dim=0)
|
||||
if snr_shift_scale is not None and snr_shift_scale > 0:
|
||||
alphas_cumprod = alphas_cumprod / (snr_shift_scale + (1 - snr_shift_scale) * alphas_cumprod)
|
||||
alphas_cumprod = alphas_cumprod / (
|
||||
snr_shift_scale + (1 - snr_shift_scale) * alphas_cumprod)
|
||||
if rescale_betas_zero_snr:
|
||||
alphas_cumprod = self.rescale_zero_terminal_snr(alphas_cumprod)
|
||||
return torch.sqrt(1 - alphas_cumprod)
|
||||
@@ -250,36 +272,73 @@ class ScaledLinearScheduler(BaseNoiseScheduler):
|
||||
return torch.sqrt(1 - torch.cumprod(1 - square_betas, dim=0))
|
||||
|
||||
def get_schedule(self):
|
||||
square_betas = torch.linspace(self.beta_min**0.5, self.beta_max**0.5, self.num_timesteps, dtype=torch.float32) ** 2
|
||||
self._sigmas = self.square_betas_to_sigmas(square_betas, self.snr_shift_scale, self.rescale_betas_zero_snr)
|
||||
square_betas = torch.linspace(self.beta_min**0.5,
|
||||
self.beta_max**0.5,
|
||||
self.num_timesteps,
|
||||
dtype=torch.float32)**2
|
||||
self._sigmas = self.square_betas_to_sigmas(square_betas,
|
||||
self.snr_shift_scale,
|
||||
self.rescale_betas_zero_snr)
|
||||
self._betas = torch.sqrt(square_betas)
|
||||
self._alphas = torch.sqrt(1 - self._sigmas ** 2)
|
||||
self._alphas = torch.sqrt(1 - self._sigmas**2)
|
||||
self._timesteps = torch.arange(len(self._sigmas), dtype=torch.float32)
|
||||
|
||||
|
||||
@NOISE_SCHEDULERS.register_class()
|
||||
class LinearScheduler(BaseNoiseScheduler):
|
||||
para_dict = {}
|
||||
|
||||
def init_params(self):
|
||||
super().init_params()
|
||||
self.beta_min = self.cfg.get('BETA_MIN', 0.00085)
|
||||
self.beta_max = self.cfg.get('BETA_MAX', 0.012)
|
||||
|
||||
def betas_to_sigmas(self, betas):
|
||||
return torch.sqrt(1 - torch.cumprod(1 - betas, dim=0))
|
||||
|
||||
def get_schedule(self):
|
||||
betas = torch.linspace(self.beta_min,
|
||||
self.beta_max,
|
||||
self.num_timesteps,
|
||||
dtype=torch.float32)
|
||||
sigmas = self.betas_to_sigmas(betas)
|
||||
self._sigmas = sigmas
|
||||
self._betas = betas
|
||||
self._alphas = torch.sqrt(1 - sigmas**2)
|
||||
self._timesteps = torch.arange(len(sigmas), dtype=torch.float32)
|
||||
|
||||
|
||||
@NOISE_SCHEDULERS.register_class()
|
||||
class FlowMatchUniformScheduler(BaseNoiseScheduler):
|
||||
def get_schedule(self):
|
||||
timesteps = np.linspace(1, self.num_timesteps, self.num_timesteps, dtype=np.float32).copy()
|
||||
timesteps = np.linspace(1,
|
||||
self.num_timesteps,
|
||||
self.num_timesteps,
|
||||
dtype=np.float32).copy()
|
||||
timesteps = torch.from_numpy(timesteps).to(dtype=torch.float32)
|
||||
self._timesteps = timesteps
|
||||
self._sigmas = self.t_to_sigma(timesteps)
|
||||
self._betas = torch.sqrt(self.sigmas_to_square_betas(self._sigmas))
|
||||
self._alphas = torch.sqrt(1 - self.betas ** 2)
|
||||
self._alphas = torch.sqrt(1 - self.betas**2)
|
||||
|
||||
def add_noise(self, x_0, noise = None, t = None):
|
||||
def add_noise(self, x_0, noise=None, t=None, **kwargs):
|
||||
if t is None:
|
||||
t = torch.rand((x_0.shape[0],), device=x_0.device)
|
||||
t = torch.rand(
|
||||
(x_0.shape[0], ), device=x_0.device) * self.num_timesteps
|
||||
sigma = self.t_to_sigma(t)
|
||||
shape = (x_0.size(0),) + (1,) * (x_0.ndim - 1)
|
||||
shape = (x_0.size(0), ) + (1, ) * (x_0.ndim - 1)
|
||||
x_t = (1 - sigma.view(shape)) * x_0 + sigma.view(shape) * noise
|
||||
return ScheduleOutput(x_0 = x_0, x_t = x_t, t = t, sigma=sigma, alpha=self.t_to_alpha(t))
|
||||
return ScheduleOutput(x_0=x_0,
|
||||
x_t=x_t,
|
||||
t=t,
|
||||
sigma=sigma,
|
||||
alpha=self.t_to_alpha(t))
|
||||
|
||||
def sigma_to_t(self, sigma, **kwargs):
|
||||
return sigma * self.num_timesteps
|
||||
|
||||
def t_to_sigma(self, t, **kwargs):
|
||||
return t/self.num_timesteps
|
||||
return t / self.num_timesteps
|
||||
|
||||
@staticmethod
|
||||
def get_config_template():
|
||||
@@ -292,21 +351,22 @@ class FlowMatchUniformScheduler(BaseNoiseScheduler):
|
||||
@NOISE_SCHEDULERS.register_class()
|
||||
class FlowMatchSigmoidScheduler(FlowMatchUniformScheduler):
|
||||
para_dict = {
|
||||
"SIGMOID_SCALE": {
|
||||
"value": 1,
|
||||
"description": "The scale for the sigmoid function."
|
||||
'SIGMOID_SCALE': {
|
||||
'value': 1,
|
||||
'description': 'The scale for the sigmoid function.'
|
||||
}
|
||||
}
|
||||
|
||||
def init_params(self):
|
||||
super().init_params()
|
||||
self.sigmoid_scale = self.cfg.get("SIGMOID_SCALE", 1)
|
||||
self.sigmoid_scale = self.cfg.get('SIGMOID_SCALE', 1)
|
||||
|
||||
def sigma_to_t(self, sigma, **kwargs):
|
||||
t = - torch.log(1/sigma - 1)/self.sigmoid_scale
|
||||
t = -torch.log(1 / sigma - 1) / self.sigmoid_scale
|
||||
return t * self.num_timesteps
|
||||
|
||||
def t_to_sigma(self, t, **kwargs):
|
||||
return torch.sigmoid(self.sigmoid_scale * t/self.num_timesteps)
|
||||
return torch.sigmoid(self.sigmoid_scale * t / self.num_timesteps)
|
||||
|
||||
@staticmethod
|
||||
def get_config_template():
|
||||
@@ -315,41 +375,46 @@ class FlowMatchSigmoidScheduler(FlowMatchUniformScheduler):
|
||||
FlowMatchSigmoidScheduler.para_dict,
|
||||
set_name=True)
|
||||
|
||||
|
||||
@NOISE_SCHEDULERS.register_class()
|
||||
class FlowMatchShiftScheduler(FlowMatchUniformScheduler):
|
||||
para_dict = {
|
||||
"SHIFT": {
|
||||
"value": 3,
|
||||
"description": "The shift factor for the timestamp."
|
||||
'SHIFT': {
|
||||
'value': 3,
|
||||
'description': 'The shift factor for the timestamp.'
|
||||
},
|
||||
"SIGMOID_SCALE": {
|
||||
"value": 1,
|
||||
"description": "The scale for the sigmoid function."
|
||||
'SIGMOID_SCALE': {
|
||||
'value': 1,
|
||||
'description': 'The scale for the sigmoid function.'
|
||||
}
|
||||
}
|
||||
|
||||
def init_params(self):
|
||||
super().init_params()
|
||||
self.shift = self.cfg.get("SHIFT", 3)
|
||||
self.sigmoid_scale = self.cfg.get("SIGMOID_SCALE", 1)
|
||||
self.shift = self.cfg.get('SHIFT', 3)
|
||||
self.sigmoid_scale = self.cfg.get('SIGMOID_SCALE', 1)
|
||||
|
||||
def add_noise(self, x_0, noise = None, t = None):
|
||||
def add_noise(self, x_0, noise=None, t=None, **kwargs):
|
||||
if t is None:
|
||||
logits_norm = torch.randn(x_0.shape[0], device=x_0.device)
|
||||
logits_norm = logits_norm * self.sigmoid_scale # larger scale for more uniform sampling
|
||||
t = logits_norm.sigmoid() * self.num_timesteps
|
||||
sigma = self.t_to_sigma(t)
|
||||
shape = (x_0.size(0),) + (1,) * (x_0.ndim - 1)
|
||||
shape = (x_0.size(0), ) + (1, ) * (x_0.ndim - 1)
|
||||
x_t = (1 - sigma.view(shape)) * x_0 + sigma.view(shape) * noise
|
||||
return ScheduleOutput(x_0 = x_0, x_t = x_t, t = t, sigma=sigma, alpha=self.t_to_alpha(t))
|
||||
return ScheduleOutput(x_0=x_0,
|
||||
x_t=x_t,
|
||||
t=t,
|
||||
sigma=sigma,
|
||||
alpha=self.t_to_alpha(t))
|
||||
|
||||
def sigma_to_t(self, sigma, **kwargs):
|
||||
t = sigma/(sigma - self.shift * sigma + self.shift)
|
||||
t = sigma / (sigma - self.shift * sigma + self.shift)
|
||||
return t * self.num_timesteps
|
||||
|
||||
def t_to_sigma(self, t, **kwargs):
|
||||
t = t / self.num_timesteps
|
||||
return (t * self.shift) / (1 + (self.shift - 1) * t)
|
||||
return (t * self.shift) / (1 + (self.shift - 1) * t)
|
||||
|
||||
@staticmethod
|
||||
def get_config_template():
|
||||
@@ -358,47 +423,53 @@ class FlowMatchShiftScheduler(FlowMatchUniformScheduler):
|
||||
FlowMatchShiftScheduler.para_dict,
|
||||
set_name=True)
|
||||
|
||||
|
||||
@NOISE_SCHEDULERS.register_class()
|
||||
class FlowMatchFluxShiftScheduler(FlowMatchUniformScheduler):
|
||||
para_dict = {
|
||||
"SHIFT": {
|
||||
"value": True,
|
||||
"description": "Use timestamp shift or not, default is True."
|
||||
'SHIFT': {
|
||||
'value': True,
|
||||
'description': 'Use timestamp shift or not, default is True.'
|
||||
},
|
||||
"SIGMOID_SCALE": {
|
||||
"value": 1,
|
||||
"description": "The scale of sigmoid function for sampling timesteps."
|
||||
'SIGMOID_SCALE': {
|
||||
'value': 1,
|
||||
'description':
|
||||
'The scale of sigmoid function for sampling timesteps.'
|
||||
},
|
||||
"BASE_SHIFT": {
|
||||
"value": 0.5,
|
||||
"description": "The base shift factor for the timestamp."
|
||||
'BASE_SHIFT': {
|
||||
'value': 0.5,
|
||||
'description': 'The base shift factor for the timestamp.'
|
||||
},
|
||||
"MAX_SHIFT": {
|
||||
"value": 1.15,
|
||||
"description": "The max shift factor for the timestamp."
|
||||
'MAX_SHIFT': {
|
||||
'value': 1.15,
|
||||
'description': 'The max shift factor for the timestamp.'
|
||||
}
|
||||
}
|
||||
|
||||
def init_params(self):
|
||||
super().init_params()
|
||||
self.shift = self.cfg.get("SHIFT", True)
|
||||
self.sigmoid_scale = self.cfg.get("SIGMOID_SCALE", 1)
|
||||
self.shift = self.cfg.get('SHIFT', True)
|
||||
self.sigmoid_scale = self.cfg.get('SIGMOID_SCALE', 1)
|
||||
self.base_shift = self.cfg.get('BASE_SHIFT', 0.5)
|
||||
self.max_shift = self.cfg.get('MAX_SHIFT', 1.15)
|
||||
|
||||
def time_shift(self, mu: float, sigma_scale: float, t: Tensor):
|
||||
return math.exp(mu) / (math.exp(mu) + (1 / t - 1) ** sigma_scale)
|
||||
return math.exp(mu) / (math.exp(mu) + (1 / t - 1)**sigma_scale)
|
||||
|
||||
def sigma_shift(self, mu: float, sigma_scale: float, sigma: Tensor):
|
||||
return 1/(torch.pow((1-sigma) * math.exp(mu)/sigma, sigma_scale) + 1)
|
||||
return 1 / (torch.pow(
|
||||
(1 - sigma) * math.exp(mu) / sigma, sigma_scale) + 1)
|
||||
|
||||
def get_lin_function(self,
|
||||
x1: float = 256, y1: float = 0.5, x2: float = 4096, y2: float = 1.15
|
||||
) -> Callable[[float], float]:
|
||||
x1: float = 256,
|
||||
y1: float = 0.5,
|
||||
x2: float = 4096,
|
||||
y2: float = 1.15) -> Callable[[float], float]:
|
||||
m = (y2 - y1) / (x2 - x1)
|
||||
b = y1 - m * x1
|
||||
return lambda x: m * x + b
|
||||
|
||||
def add_noise(self, x_0, noise = None, t = None):
|
||||
def add_noise(self, x_0, noise=None, t=None, **kwargs):
|
||||
if x_0.ndim == 3:
|
||||
seq_len = x_0.shape[2] // 4
|
||||
else:
|
||||
@@ -409,23 +480,29 @@ class FlowMatchFluxShiftScheduler(FlowMatchUniformScheduler):
|
||||
logits_norm = logits_norm * self.sigmoid_scale # larger scale for more uniform sampling
|
||||
t = logits_norm.sigmoid() * self.num_timesteps
|
||||
sigma = self.t_to_sigma(t, seq_len=seq_len)
|
||||
shape = (x_0.size(0),) + (1,) * (x_0.ndim - 1)
|
||||
shape = (x_0.size(0), ) + (1, ) * (x_0.ndim - 1)
|
||||
x_t = (1 - sigma.view(shape)) * x_0 + sigma.view(shape) * noise
|
||||
return ScheduleOutput(x_0 = x_0, x_t = x_t, t = t, sigma=sigma, alpha=self.t_to_alpha(t))
|
||||
return ScheduleOutput(x_0=x_0,
|
||||
x_t=x_t,
|
||||
t=t,
|
||||
sigma=sigma,
|
||||
alpha=self.t_to_alpha(t))
|
||||
|
||||
def sigma_to_t(self, sigma, **kwargs):
|
||||
seq_len = kwargs.get('seq_len', 256)
|
||||
if self.shift:
|
||||
mu = self.get_lin_function(y1=self.base_shift, y2=self.max_shift)(seq_len)
|
||||
mu = self.get_lin_function(y1=self.base_shift,
|
||||
y2=self.max_shift)(seq_len)
|
||||
sigma = self.sigma_shift(mu, 1.0, sigma)
|
||||
t = torch.as_tensor(sigma, dtype=torch.float32)
|
||||
return t * self.num_timesteps
|
||||
|
||||
def t_to_sigma(self, t, **kwargs):
|
||||
seq_len = kwargs.get('seq_len', 256)
|
||||
t = t/self.num_timesteps
|
||||
t = t / self.num_timesteps
|
||||
if self.shift:
|
||||
mu = self.get_lin_function(y1=self.base_shift, y2=self.max_shift)(seq_len)
|
||||
mu = self.get_lin_function(y1=self.base_shift,
|
||||
y2=self.max_shift)(seq_len)
|
||||
t = self.time_shift(mu, 1.0, t)
|
||||
sigma = torch.as_tensor(t, dtype=torch.float32)
|
||||
return sigma
|
||||
@@ -437,71 +514,94 @@ class FlowMatchFluxShiftScheduler(FlowMatchUniformScheduler):
|
||||
FlowMatchFluxShiftScheduler.para_dict,
|
||||
set_name=True)
|
||||
|
||||
|
||||
@NOISE_SCHEDULERS.register_class()
|
||||
class FlowMatchSigmaScheduler(FlowMatchUniformScheduler):
|
||||
para_dict = {
|
||||
"WEIGHTING_SCHEME" : {
|
||||
"value": "logit_normal",
|
||||
"description": "The weighting scheme for sampling timesteps, "
|
||||
"choose from ['sigma_sqrt', 'logit_normal', 'mode', 'cosmap', 'none']."
|
||||
'WEIGHTING_SCHEME': {
|
||||
'value':
|
||||
'logit_normal',
|
||||
'description':
|
||||
'The weighting scheme for sampling timesteps, '
|
||||
"choose from ['sigma_sqrt', 'logit_normal', 'mode', 'cosmap', 'none']."
|
||||
},
|
||||
"SHIFT": {
|
||||
"value": 3.0,
|
||||
"description": "The shift factor for the timestamp."
|
||||
'SHIFT': {
|
||||
'value': 3.0,
|
||||
'description': 'The shift factor for the timestamp.'
|
||||
},
|
||||
"LOGIT_MEAN" : {
|
||||
"value": 0.0,
|
||||
"description": "The mean of the logit distribution for sampling timesteps."
|
||||
'LOGIT_MEAN': {
|
||||
'value':
|
||||
0.0,
|
||||
'description':
|
||||
'The mean of the logit distribution for sampling timesteps.'
|
||||
},
|
||||
"LOGIT_STD" : {
|
||||
"value": 1.0,
|
||||
"description": "The standard deviation of the logit distribution for sampling timesteps."
|
||||
'LOGIT_STD': {
|
||||
'value':
|
||||
1.0,
|
||||
'description':
|
||||
'The standard deviation of the logit distribution for sampling timesteps.'
|
||||
},
|
||||
"MODE_SCALE" : {
|
||||
"value": 1.29,
|
||||
"description": "The scale factor for the mode of the logit distribution for sampling timesteps."
|
||||
'MODE_SCALE': {
|
||||
'value':
|
||||
1.29,
|
||||
'description':
|
||||
'The scale factor for the mode of the logit distribution for sampling timesteps.'
|
||||
}
|
||||
}
|
||||
|
||||
def init_params(self):
|
||||
super().init_params()
|
||||
self.weighting_scheme = self.cfg.get("WEIGHTING_SCHEME", "logit_normal")
|
||||
self.logit_mean = self.cfg.get("LOGIT_MEAN", 0.0)
|
||||
self.logit_std = self.cfg.get("LOGIT_STD", 1.0)
|
||||
self.mode_scale = self.cfg.get("MODE_SCALE", 1.29)
|
||||
self.shift = self.cfg.get("SHIFT", 1.0)
|
||||
self.weighting_scheme = self.cfg.get('WEIGHTING_SCHEME',
|
||||
'logit_normal')
|
||||
self.logit_mean = self.cfg.get('LOGIT_MEAN', 0.0)
|
||||
self.logit_std = self.cfg.get('LOGIT_STD', 1.0)
|
||||
self.mode_scale = self.cfg.get('MODE_SCALE', 1.29)
|
||||
self.shift = self.cfg.get('SHIFT', 1.0)
|
||||
|
||||
def get_schedule(self):
|
||||
timesteps = np.linspace(1, self.num_timesteps, self.num_timesteps, dtype=np.float32).copy()
|
||||
timesteps = np.linspace(1,
|
||||
self.num_timesteps,
|
||||
self.num_timesteps,
|
||||
dtype=np.float32).copy()
|
||||
timesteps = torch.from_numpy(timesteps).to(dtype=torch.float32)
|
||||
self._timesteps = timesteps
|
||||
timesteps = timesteps / self.num_timesteps
|
||||
self._sigmas = self.shift * timesteps / (1 + (self.shift - 1) * timesteps)
|
||||
self._sigmas = self.shift * timesteps / (1 +
|
||||
(self.shift - 1) * timesteps)
|
||||
self._betas = torch.sqrt(self.sigmas_to_square_betas(self._sigmas))
|
||||
self._alphas = torch.sqrt(1 - self.betas ** 2)
|
||||
self._alphas = torch.sqrt(1 - self.betas**2)
|
||||
|
||||
def add_noise(self, x_0, noise=None, t=None):
|
||||
def add_noise(self, x_0, noise=None, t=None, **kwargs):
|
||||
if t is None:
|
||||
if self.weighting_scheme == "logit_normal":
|
||||
t = torch.normal(mean=self.logit_mean, std=self.logit_std, size=(x_0.shape[0],), device=x_0.device)
|
||||
if self.weighting_scheme == 'logit_normal':
|
||||
t = torch.normal(mean=self.logit_mean,
|
||||
std=self.logit_std,
|
||||
size=(x_0.shape[0], ),
|
||||
device=x_0.device)
|
||||
else:
|
||||
t = torch.rand(x_0.shape[0], device=x_0.device)
|
||||
t = self.compute_density_for_timestep_sampling(t) * self.num_timesteps
|
||||
t = self.compute_density_for_timestep_sampling(
|
||||
t) * self.num_timesteps
|
||||
sigma = self.t_to_sigma(t)
|
||||
shape = (x_0.size(0),) + (1,) * (x_0.ndim - 1)
|
||||
shape = (x_0.size(0), ) + (1, ) * (x_0.ndim - 1)
|
||||
x_t = (1 - sigma.view(shape)) * x_0 + sigma.view(shape) * noise
|
||||
return ScheduleOutput(x_0=x_0, x_t=x_t, t=t, sigma=sigma, alpha=self.t_to_alpha(t))
|
||||
return ScheduleOutput(x_0=x_0,
|
||||
x_t=x_t,
|
||||
t=t,
|
||||
sigma=sigma,
|
||||
alpha=self.t_to_alpha(t))
|
||||
|
||||
def compute_density_for_timestep_sampling(self, t):
|
||||
"""Compute the density for sampling the timesteps when doing SD3 training.
|
||||
Courtesy: This was contributed by Rafie Walker in https://github.com/huggingface/diffusers/pull/8528.
|
||||
SD3 paper reference: https://arxiv.org/abs/2403.03206v1.
|
||||
"""
|
||||
if self.weighting_scheme == "logit_normal":
|
||||
if self.weighting_scheme == 'logit_normal':
|
||||
# See 3.1 in the SD3 paper ($rf/lognorm(0.00,1.00)$).
|
||||
t = torch.nn.functional.sigmoid(t)
|
||||
elif self.weighting_scheme == "mode":
|
||||
t = 1 - t - self.mode_scale * (torch.cos(math.pi * t / 2) ** 2 - 1 + t)
|
||||
elif self.weighting_scheme == 'mode':
|
||||
t = 1 - t - self.mode_scale * (torch.cos(math.pi * t / 2)**2 - 1 +
|
||||
t)
|
||||
return t
|
||||
|
||||
def sigma_to_t(self, sigma, **kwargs):
|
||||
@@ -511,7 +611,8 @@ class FlowMatchSigmaScheduler(FlowMatchUniformScheduler):
|
||||
indices = t.long()
|
||||
indices[indices >= self.num_timesteps] = self.num_timesteps - 1
|
||||
timesteps = self.timesteps.to(t)[indices]
|
||||
step_indices = [(self.timesteps.to(t) == t).nonzero().item() for t in timesteps]
|
||||
step_indices = [(self.timesteps.to(t) == t).nonzero().item()
|
||||
for t in timesteps]
|
||||
sigma = self.sigmas[step_indices].flatten().to(t)
|
||||
return sigma
|
||||
|
||||
@@ -526,8 +627,9 @@ class FlowMatchSigmaScheduler(FlowMatchUniformScheduler):
|
||||
if __name__ == '__main__':
|
||||
from scepter.modules.utils.config import Config
|
||||
cfg = Config(cfg_dict={
|
||||
"NAME": "FlowMatchShiftScheduler",
|
||||
"SHIFT": 1.15
|
||||
}, load=False)
|
||||
'NAME': 'FlowMatchShiftScheduler',
|
||||
'SHIFT': 1.15
|
||||
},
|
||||
load=False)
|
||||
|
||||
scheduler = NOISE_SCHEDULERS.build(cfg)
|
||||
|
||||
@@ -1,10 +1,13 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import torch
|
||||
|
||||
|
||||
def _i(tensor, t, x):
|
||||
"""
|
||||
Index tensor using t and format the output according to x.
|
||||
"""
|
||||
shape = (x.size(0),) + (1,) * (x.ndim - 1)
|
||||
shape = (x.size(0), ) + (1, ) * (x.ndim - 1)
|
||||
if isinstance(t, torch.Tensor):
|
||||
t = t.to(tensor.device)
|
||||
return tensor[t].view(shape).to(x.device)
|
||||
return tensor[t].view(shape).to(x.device)
|
||||
|
||||
@@ -9,8 +9,11 @@ import numpy as np
|
||||
import open_clip
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
import torch.utils.dlpack
|
||||
from einops import rearrange
|
||||
from torch.utils.checkpoint import checkpoint
|
||||
|
||||
from scepter.modules.model.backbone.unet.unet_utils import Timestep
|
||||
from scepter.modules.model.embedder.base_embedder import BaseEmbedder
|
||||
from scepter.modules.model.embedder.resampler import Resampler
|
||||
@@ -21,7 +24,6 @@ from scepter.modules.model.utils.basic_utils import expand_dims_like
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
from torch.utils.checkpoint import checkpoint
|
||||
|
||||
try:
|
||||
from transformers import (CLIPTextModel, CLIPTokenizer,
|
||||
@@ -831,22 +833,30 @@ class T5EmbedderHF(BaseEmbedder):
|
||||
def __init__(self, cfg, logger=None):
|
||||
super().__init__(cfg, logger=logger)
|
||||
pretrained_path = cfg.get('PRETRAINED_MODEL', None)
|
||||
t5_dtype = cfg.get('T5_DTYPE', None)
|
||||
self.t5_dtype = cfg.get('T5_DTYPE', 'float32')
|
||||
assert pretrained_path
|
||||
with FS.get_dir_to_local_dir(pretrained_path,
|
||||
wait_finish=True) as local_path:
|
||||
if t5_dtype is not None:
|
||||
self.model = T5EncoderModel.from_pretrained(
|
||||
local_path, torch_dtype=getattr(torch, t5_dtype))
|
||||
else:
|
||||
self.model = T5EncoderModel.from_pretrained(local_path)
|
||||
self.model = T5EncoderModel.from_pretrained(
|
||||
local_path,
|
||||
torch_dtype=getattr(
|
||||
torch,
|
||||
'float' if self.t5_dtype == 'float32' else self.t5_dtype))
|
||||
tokenizer_path = cfg.get('TOKENIZER_PATH', None)
|
||||
self.length = cfg.get('LENGTH', 77)
|
||||
|
||||
self.use_grad = cfg.get('USE_GRAD', False)
|
||||
self.clean = cfg.get('CLEAN', 'whitespace')
|
||||
self.added_identifier = cfg.get('ADDED_IDENTIFIER', None)
|
||||
if tokenizer_path:
|
||||
self.tokenize_kargs = {'return_tensors': 'pt'}
|
||||
with FS.get_dir_to_local_dir(tokenizer_path,
|
||||
wait_finish=True) as local_path:
|
||||
self.tokenizer = AutoTokenizer.from_pretrained(local_path)
|
||||
if self.added_identifier is not None and isinstance(
|
||||
self.added_identifier, list):
|
||||
self.tokenizer = AutoTokenizer.from_pretrained(local_path)
|
||||
else:
|
||||
self.tokenizer = AutoTokenizer.from_pretrained(local_path)
|
||||
if self.length is not None:
|
||||
self.tokenize_kargs.update({
|
||||
'padding': 'max_length',
|
||||
@@ -868,12 +878,15 @@ class T5EmbedderHF(BaseEmbedder):
|
||||
param.requires_grad = False
|
||||
|
||||
# encode && encode_text
|
||||
def forward(self, tokens, return_mask=False):
|
||||
def forward(self, tokens, return_mask=False, use_mask=True):
|
||||
# tokenization
|
||||
embedding_context = nullcontext if self.use_grad else torch.no_grad
|
||||
with embedding_context():
|
||||
x = self.model(tokens.input_ids.to(we.device_id),
|
||||
tokens.attention_mask.to(we.device_id))
|
||||
if use_mask:
|
||||
x = self.model(tokens.input_ids.to(we.device_id),
|
||||
tokens.attention_mask.to(we.device_id))
|
||||
else:
|
||||
x = self.model(tokens.input_ids.to(we.device_id))
|
||||
x = x.last_hidden_state
|
||||
# if not self.return_pooled:
|
||||
# return x.detach()
|
||||
@@ -882,7 +895,7 @@ class T5EmbedderHF(BaseEmbedder):
|
||||
if return_mask:
|
||||
return x.detach() + 0.0, tokens.attention_mask.to(we.device_id)
|
||||
else:
|
||||
return x.detach() + 0.0
|
||||
return x.detach() + 0.0, None
|
||||
|
||||
def pool(self, x, tokens):
|
||||
# take features from the eot embedding (eot_token is the highest number in each sequence)
|
||||
@@ -897,7 +910,7 @@ class T5EmbedderHF(BaseEmbedder):
|
||||
elif self.clean == 'canonicalize':
|
||||
text = canonicalize(basic_clean(text))
|
||||
elif self.clean == 'heavy':
|
||||
text = heavy_clean(heavy_clean(text))
|
||||
text = heavy_clean(basic_clean(text))
|
||||
return text
|
||||
|
||||
def encode_text(self,
|
||||
@@ -907,14 +920,90 @@ class T5EmbedderHF(BaseEmbedder):
|
||||
return_mask=False):
|
||||
return self(tokens, return_mask=return_mask)
|
||||
|
||||
def encode(self, text, return_mask=False):
|
||||
def encode(self, text, return_mask=False, use_mask=True):
|
||||
if isinstance(text, str):
|
||||
text = [text]
|
||||
if self.clean:
|
||||
text = [self._clean(u) for u in text]
|
||||
assert self.tokenizer is not None
|
||||
tokens = self.tokenizer(text, **self.tokenize_kargs)
|
||||
return self(tokens, return_mask=return_mask)
|
||||
cont, mask = [], []
|
||||
with torch.autocast(device_type='cuda',
|
||||
enabled=self.t5_dtype in ('float16', 'bfloat16'),
|
||||
dtype=getattr(torch, self.t5_dtype)):
|
||||
for tt in text:
|
||||
tokens = self.tokenizer([tt], **self.tokenize_kargs)
|
||||
one_cont, one_mask = self(tokens,
|
||||
return_mask=return_mask,
|
||||
use_mask=use_mask)
|
||||
cont.append(one_cont)
|
||||
mask.append(one_mask)
|
||||
if return_mask:
|
||||
return torch.cat(cont, dim=0), torch.cat(mask, dim=0)
|
||||
else:
|
||||
return torch.cat(cont, dim=0)
|
||||
|
||||
def encode_longlist(self, text_list, return_mask=True):
|
||||
text_max_len = max([len(p) for p in text_list]) * self.length
|
||||
cont_list, cont_mask_list = [], []
|
||||
for pp in text_list:
|
||||
cont, cont_mask = self.encode(pp, return_mask=return_mask)
|
||||
cont_channel, cont_dim = cont.shape[0] * cont.shape[1], cont.shape[
|
||||
2]
|
||||
cont = cont.view(cont_channel, cont_dim)
|
||||
cont_mask_channel = cont_mask.shape[0] * cont_mask.shape[1]
|
||||
cont_mask = cont_mask.view(cont_mask_channel)
|
||||
select_cont = cont[cont_mask == 1]
|
||||
select_cont_mask, _ = torch.sort(cont_mask, dim=0, descending=True)
|
||||
if select_cont.shape[0] != text_max_len:
|
||||
select_cont = F.pad(
|
||||
select_cont,
|
||||
(0, 0, 0, text_max_len - select_cont.shape[0]))
|
||||
if select_cont_mask.shape[0] != text_max_len:
|
||||
select_cont_mask = F.pad(
|
||||
select_cont_mask,
|
||||
(0, text_max_len - select_cont_mask.shape[0]))
|
||||
cont_list.append(select_cont)
|
||||
cont_mask_list.append(select_cont_mask)
|
||||
return torch.stack(cont_list), torch.stack(cont_mask_list)
|
||||
|
||||
def encode_longlist_v1(self, text_list, return_mask=True):
|
||||
cont_list = []
|
||||
max_len = 0
|
||||
for pp in text_list:
|
||||
cont, cont_mask = self.encode(pp, return_mask=True)
|
||||
txt_lens = cont_mask.flatten(start_dim=1).sum(dim=-1)
|
||||
pp_cont = torch.cat(
|
||||
[c[:txt_len] for c, txt_len in zip(cont, txt_lens)], dim=0)
|
||||
max_len = pp_cont.size(0) if pp_cont.size(0) > max_len else max_len
|
||||
cont_list.append(pp_cont)
|
||||
cont = torch.cat([
|
||||
torch.cat([c, c.new_zeros(max_len - c.size(0), c.size(1))],
|
||||
dim=0).unsqueeze(0) for c in cont_list
|
||||
],
|
||||
dim=0)
|
||||
if return_mask:
|
||||
cont_mask = torch.cat([
|
||||
torch.cat(
|
||||
[c.new_ones(c.size(0)),
|
||||
c.new_zeros(max_len - c.size(0))],
|
||||
dim=-1).unsqueeze(0) for c in cont_list
|
||||
],
|
||||
dim=0).type(torch.long, non_blocking=True)
|
||||
return cont, cont_mask
|
||||
else:
|
||||
return cont
|
||||
|
||||
def encode_list(self, text_list, return_mask=True):
|
||||
cont_list = []
|
||||
mask_list = []
|
||||
for pp in text_list:
|
||||
cont, cont_mask = self.encode(pp, return_mask=return_mask)
|
||||
cont_list.append(cont)
|
||||
mask_list.append(cont_mask)
|
||||
if return_mask:
|
||||
return cont_list, mask_list
|
||||
else:
|
||||
return cont_list
|
||||
|
||||
@staticmethod
|
||||
def get_config_template():
|
||||
|
||||
@@ -1,99 +1,109 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import torch
|
||||
import transformers
|
||||
from scepter.modules.model.embedder.base_embedder import BaseEmbedder
|
||||
from scepter.modules.model.registry import EMBEDDERS
|
||||
from scepter.modules.model.tokenizer.tokenizer_component import whitespace_clean, basic_clean, canonicalize
|
||||
from scepter.modules.model.tokenizer.tokenizer_component import (
|
||||
basic_clean, canonicalize, whitespace_clean)
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
import transformers
|
||||
from scepter.modules.utils.file_system import FS
|
||||
|
||||
|
||||
@EMBEDDERS.register_class()
|
||||
class HFEmbedder(BaseEmbedder):
|
||||
para_dict = {
|
||||
"HF_MODEL_CLS": {
|
||||
"value": None,
|
||||
"description": "huggingface cls in transfomer"
|
||||
'HF_MODEL_CLS': {
|
||||
'value': None,
|
||||
'description': 'huggingface cls in transfomer'
|
||||
},
|
||||
"MODEL_PATH": {
|
||||
"value": None,
|
||||
"description": "model folder path"
|
||||
'MODEL_PATH': {
|
||||
'value': None,
|
||||
'description': 'model folder path'
|
||||
},
|
||||
"HF_TOKENIZER_CLS": {
|
||||
"value": None,
|
||||
"description": "huggingface cls in transfomer"
|
||||
'HF_TOKENIZER_CLS': {
|
||||
'value': None,
|
||||
'description': 'huggingface cls in transfomer'
|
||||
},
|
||||
|
||||
"TOKENIZER_PATH": {
|
||||
"value": None,
|
||||
"description": "tokenizer folder path"
|
||||
'TOKENIZER_PATH': {
|
||||
'value': None,
|
||||
'description': 'tokenizer folder path'
|
||||
},
|
||||
"MAX_LENGTH": {
|
||||
"value": 77,
|
||||
"description": "max length of input"
|
||||
'MAX_LENGTH': {
|
||||
'value': 77,
|
||||
'description': 'max length of input'
|
||||
},
|
||||
"OUTPUT_KEY": {
|
||||
"value": "last_hidden_state",
|
||||
"description": "output key"
|
||||
'OUTPUT_KEY': {
|
||||
'value': 'last_hidden_state',
|
||||
'description': 'output key'
|
||||
},
|
||||
"D_TYPE": {
|
||||
"value": "float",
|
||||
"description": "dtype"
|
||||
'D_TYPE': {
|
||||
'value': 'float',
|
||||
'description': 'dtype'
|
||||
},
|
||||
"BATCH_INFER": {
|
||||
"value": False,
|
||||
"description": "batch infer"
|
||||
'BATCH_INFER': {
|
||||
'value': False,
|
||||
'description': 'batch infer'
|
||||
}
|
||||
}
|
||||
para_dict.update(BaseEmbedder.para_dict)
|
||||
|
||||
def __init__(self, cfg, logger=None):
|
||||
super().__init__(cfg, logger=logger)
|
||||
hf_model_cls = cfg.get('HF_MODEL_CLS', None)
|
||||
model_path = cfg.get("MODEL_PATH", None)
|
||||
model_path = cfg.get('MODEL_PATH', None)
|
||||
hf_tokenizer_cls = cfg.get('HF_TOKENIZER_CLS', None)
|
||||
tokenizer_path = cfg.get('TOKENIZER_PATH', None)
|
||||
self.max_length = cfg.get('MAX_LENGTH', 77)
|
||||
self.output_key = cfg.get("OUTPUT_KEY", "last_hidden_state")
|
||||
self.d_type = cfg.get("D_TYPE", "float")
|
||||
self.clean = cfg.get("CLEAN", "whitespace")
|
||||
self.batch_infer = cfg.get("BATCH_INFER", False)
|
||||
self.output_key = cfg.get('OUTPUT_KEY', 'last_hidden_state')
|
||||
self.d_type = cfg.get('D_TYPE', 'float')
|
||||
self.clean = cfg.get('CLEAN', 'whitespace')
|
||||
self.batch_infer = cfg.get('BATCH_INFER', False)
|
||||
torch_dtype = getattr(torch, self.d_type)
|
||||
|
||||
assert hf_model_cls is not None and hf_tokenizer_cls is not None
|
||||
assert model_path is not None and tokenizer_path is not None
|
||||
|
||||
with FS.get_dir_to_local_dir(tokenizer_path, wait_finish=True) as local_path:
|
||||
self.tokenizer = getattr(transformers, hf_tokenizer_cls).from_pretrained(local_path,
|
||||
max_length = self.max_length,
|
||||
torch_dtype = torch_dtype)
|
||||
|
||||
with FS.get_dir_to_local_dir(model_path, wait_finish=True) as local_path:
|
||||
self.hf_module = getattr(transformers, hf_model_cls).from_pretrained(local_path, torch_dtype = torch_dtype)
|
||||
with FS.get_dir_to_local_dir(tokenizer_path,
|
||||
wait_finish=True) as local_path:
|
||||
self.tokenizer = getattr(transformers,
|
||||
hf_tokenizer_cls).from_pretrained(
|
||||
local_path,
|
||||
max_length=self.max_length,
|
||||
torch_dtype=torch_dtype)
|
||||
|
||||
with FS.get_dir_to_local_dir(model_path,
|
||||
wait_finish=True) as local_path:
|
||||
self.hf_module = getattr(transformers,
|
||||
hf_model_cls).from_pretrained(
|
||||
local_path, torch_dtype=torch_dtype)
|
||||
|
||||
self.hf_module = self.hf_module.eval().requires_grad_(False)
|
||||
|
||||
def forward(self, text: list[str], return_mask = False):
|
||||
def forward(self, text: list[str], return_mask=False):
|
||||
batch_encoding = self.tokenizer(
|
||||
text,
|
||||
truncation=True,
|
||||
max_length=self.max_length,
|
||||
return_length=False,
|
||||
return_overflowing_tokens=False,
|
||||
padding="max_length",
|
||||
return_tensors="pt",
|
||||
padding='max_length',
|
||||
return_tensors='pt',
|
||||
)
|
||||
|
||||
outputs = self.hf_module(
|
||||
input_ids=batch_encoding["input_ids"].to(self.hf_module.device),
|
||||
input_ids=batch_encoding['input_ids'].to(self.hf_module.device),
|
||||
attention_mask=None,
|
||||
output_hidden_states=False,
|
||||
)
|
||||
if return_mask:
|
||||
return outputs[self.output_key], batch_encoding['attention_mask'].to(self.hf_module.device)
|
||||
return outputs[
|
||||
self.output_key], batch_encoding['attention_mask'].to(
|
||||
self.hf_module.device)
|
||||
else:
|
||||
return outputs[self.output_key], None
|
||||
|
||||
def encode(self, text, return_mask = False):
|
||||
def encode(self, text, return_mask=False):
|
||||
if isinstance(text, str):
|
||||
text = [text]
|
||||
if self.clean:
|
||||
@@ -109,13 +119,12 @@ class HFEmbedder(BaseEmbedder):
|
||||
else:
|
||||
return torch.cat(cont, dim=0)
|
||||
else:
|
||||
ret_data = self(text, return_mask = return_mask)
|
||||
ret_data = self(text, return_mask=return_mask)
|
||||
if return_mask:
|
||||
return ret_data
|
||||
else:
|
||||
return ret_data[0]
|
||||
|
||||
|
||||
def _clean(self, text):
|
||||
if self.clean == 'whitespace':
|
||||
text = whitespace_clean(basic_clean(text))
|
||||
@@ -124,6 +133,7 @@ class HFEmbedder(BaseEmbedder):
|
||||
elif self.clean == 'canonicalize':
|
||||
text = canonicalize(basic_clean(text))
|
||||
return text
|
||||
|
||||
@staticmethod
|
||||
def get_config_template():
|
||||
return dict_to_yaml('EMBEDDER',
|
||||
@@ -131,15 +141,13 @@ class HFEmbedder(BaseEmbedder):
|
||||
HFEmbedder.para_dict,
|
||||
set_name=True)
|
||||
|
||||
|
||||
@EMBEDDERS.register_class()
|
||||
class T5PlusClipFluxEmbedder(BaseEmbedder):
|
||||
"""
|
||||
Uses the OpenCLIP transformer encoder for text
|
||||
"""
|
||||
para_dict = {
|
||||
'T5_MODEL': {},
|
||||
'CLIP_MODEL': {}
|
||||
}
|
||||
para_dict = {'T5_MODEL': {}, 'CLIP_MODEL': {}}
|
||||
|
||||
def __init__(self, cfg, logger=None):
|
||||
super().__init__(cfg, logger=logger)
|
||||
@@ -147,8 +155,8 @@ class T5PlusClipFluxEmbedder(BaseEmbedder):
|
||||
self.clip_model = EMBEDDERS.build(cfg.CLIP_MODEL, logger=logger)
|
||||
|
||||
def encode(self, text):
|
||||
t5_embeds = self.t5_model.encode(text, return_mask = False)
|
||||
clip_embeds = self.clip_model.encode(text, return_mask = False)
|
||||
t5_embeds = self.t5_model.encode(text, return_mask=False)
|
||||
clip_embeds = self.clip_model.encode(text, return_mask=False)
|
||||
# change embedding strategy here
|
||||
return {
|
||||
'context': t5_embeds,
|
||||
@@ -160,4 +168,4 @@ class T5PlusClipFluxEmbedder(BaseEmbedder):
|
||||
return dict_to_yaml('EMBEDDER',
|
||||
__class__.__name__,
|
||||
T5PlusClipFluxEmbedder.para_dict,
|
||||
set_name=True)
|
||||
set_name=True)
|
||||
|
||||
@@ -1,6 +1,7 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from scepter.modules.model.network.ldm.ldm import LatentDiffusion
|
||||
from scepter.modules.model.network.ldm.ldm_ace import LatentDiffusionACE
|
||||
from scepter.modules.model.network.ldm.ldm_edit import LatentDiffusionEdit
|
||||
from scepter.modules.model.network.ldm.ldm_pixart import LatentDiffusionPixart
|
||||
from scepter.modules.model.network.ldm.ldm_sce import (
|
||||
|
||||
@@ -0,0 +1,351 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import copy
|
||||
import random
|
||||
from contextlib import nullcontext
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from torch import nn
|
||||
|
||||
from scepter.modules.model.network.ldm import LatentDiffusion
|
||||
from scepter.modules.model.registry import MODELS
|
||||
from scepter.modules.model.utils.basic_utils import check_list_of_list
|
||||
from scepter.modules.model.utils.basic_utils import \
|
||||
pack_imagelist_into_tensor_v2 as pack_imagelist_into_tensor
|
||||
from scepter.modules.model.utils.basic_utils import (
|
||||
to_device, unpack_tensor_into_imagelist)
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.utils.distribute import we
|
||||
|
||||
|
||||
class TextEmbedding(nn.Module):
|
||||
def __init__(self, embedding_shape):
|
||||
super().__init__()
|
||||
self.pos = nn.Parameter(data=torch.zeros(embedding_shape))
|
||||
|
||||
|
||||
@MODELS.register_class()
|
||||
class LatentDiffusionACE(LatentDiffusion):
|
||||
para_dict = LatentDiffusion.para_dict
|
||||
para_dict['DECODER_BIAS'] = {'value': 0, 'description': ''}
|
||||
|
||||
def __init__(self, cfg, logger=None):
|
||||
super().__init__(cfg, logger=logger)
|
||||
self.interpolate_func = lambda x: (F.interpolate(
|
||||
x.unsqueeze(0),
|
||||
scale_factor=1 / self.size_factor,
|
||||
mode='nearest-exact') if x is not None else None)
|
||||
|
||||
self.text_indentifers = cfg.get('TEXT_IDENTIFIER', [])
|
||||
self.use_text_pos_embeddings = cfg.get('USE_TEXT_POS_EMBEDDINGS',
|
||||
False)
|
||||
if self.use_text_pos_embeddings:
|
||||
self.text_position_embeddings = TextEmbedding(
|
||||
(10, 4096)).eval().requires_grad_(False)
|
||||
else:
|
||||
self.text_position_embeddings = None
|
||||
|
||||
self.logger.info(self.model)
|
||||
|
||||
@torch.no_grad()
|
||||
def encode_first_stage(self, x, **kwargs):
|
||||
return [
|
||||
self.scale_factor *
|
||||
self.first_stage_model._encode(i.unsqueeze(0).to(torch.float16))
|
||||
for i in x
|
||||
]
|
||||
|
||||
@torch.no_grad()
|
||||
def decode_first_stage(self, z):
|
||||
return [
|
||||
self.first_stage_model._decode(1. / self.scale_factor *
|
||||
i.to(torch.float16)) for i in z
|
||||
]
|
||||
|
||||
def cond_stage_embeddings(self, prompt, edit_image, cont, cont_mask):
|
||||
if self.use_text_pos_embeddings and not torch.sum(
|
||||
self.text_position_embeddings.pos) > 0:
|
||||
identifier_cont, identifier_cont_mask = getattr(
|
||||
self.cond_stage_model, 'encode')(self.text_indentifers,
|
||||
return_mask=True)
|
||||
self.text_position_embeddings.load_state_dict(
|
||||
{'pos': identifier_cont[:, 0, :]})
|
||||
cont_, cont_mask_ = [], []
|
||||
for pp, edit, c, cm in zip(prompt, edit_image, cont, cont_mask):
|
||||
if isinstance(pp, list):
|
||||
cont_.append([c[-1], *c] if len(edit) > 0 else [c[-1]])
|
||||
cont_mask_.append([cm[-1], *cm] if len(edit) > 0 else [cm[-1]])
|
||||
else:
|
||||
raise NotImplementedError
|
||||
|
||||
return cont_, cont_mask_
|
||||
|
||||
def limit_batch_data(self, batch_data_list, log_num):
|
||||
if log_num and log_num > 0:
|
||||
batch_data_list_limited = []
|
||||
for sub_data in batch_data_list:
|
||||
if sub_data is not None:
|
||||
sub_data = sub_data[:log_num]
|
||||
batch_data_list_limited.append(sub_data)
|
||||
return batch_data_list_limited
|
||||
else:
|
||||
return batch_data_list
|
||||
|
||||
def forward_train(self,
|
||||
edit_image=[],
|
||||
edit_image_mask=[],
|
||||
image=None,
|
||||
image_mask=None,
|
||||
noise=None,
|
||||
prompt=[],
|
||||
**kwargs):
|
||||
'''
|
||||
Args:
|
||||
edit_image: list of list of edit_image
|
||||
edit_image_mask: list of list of edit_image_mask
|
||||
image: target image
|
||||
image_mask: target image mask
|
||||
noise: default is None, generate automaticly
|
||||
prompt: list of list of text
|
||||
**kwargs:
|
||||
Returns:
|
||||
'''
|
||||
assert check_list_of_list(prompt) and check_list_of_list(
|
||||
edit_image) and check_list_of_list(edit_image_mask)
|
||||
assert len(edit_image) == len(edit_image_mask) == len(prompt)
|
||||
assert self.cond_stage_model is not None
|
||||
gc_seg = kwargs.pop('gc_seg', [])
|
||||
gc_seg = int(gc_seg[0]) if len(gc_seg) > 0 else 0
|
||||
context = {}
|
||||
|
||||
# process image
|
||||
image = to_device(image)
|
||||
x_start = self.encode_first_stage(image, **kwargs)
|
||||
x_start, x_shapes = pack_imagelist_into_tensor(x_start) # B, C, L
|
||||
n, _, _ = x_start.shape
|
||||
t = torch.randint(0, self.num_timesteps, (n, ),
|
||||
device=x_start.device).long()
|
||||
context['x_shapes'] = x_shapes
|
||||
|
||||
# process image mask
|
||||
image_mask = to_device(image_mask, strict=False)
|
||||
context['x_mask'] = [self.interpolate_func(i) for i in image_mask
|
||||
] if image_mask is not None else [None] * n
|
||||
|
||||
# process text
|
||||
# with torch.autocast(device_type="cuda", enabled=True, dtype=torch.bfloat16):
|
||||
prompt_ = [[pp] if isinstance(pp, str) else pp for pp in prompt]
|
||||
try:
|
||||
cont, cont_mask = getattr(self.cond_stage_model,
|
||||
'encode_list')(prompt_, return_mask=True)
|
||||
except Exception as e:
|
||||
print(e, prompt_)
|
||||
cont, cont_mask = self.cond_stage_embeddings(prompt, edit_image, cont,
|
||||
cont_mask)
|
||||
context['crossattn'] = cont
|
||||
|
||||
# process edit image & edit image mask
|
||||
edit_image = [to_device(i, strict=False) for i in edit_image]
|
||||
edit_image_mask = [to_device(i, strict=False) for i in edit_image_mask]
|
||||
e_img, e_mask = [], []
|
||||
for u, m in zip(edit_image, edit_image_mask):
|
||||
if m is None:
|
||||
m = [None] * len(u) if u is not None else [None]
|
||||
e_img.append(
|
||||
self.encode_first_stage(u, **kwargs) if u is not None else u)
|
||||
e_mask.append([
|
||||
self.interpolate_func(i) if i is not None else None for i in m
|
||||
])
|
||||
context['edit'], context['edit_mask'] = e_img, e_mask
|
||||
|
||||
# process loss
|
||||
loss = self.diffusion.loss(
|
||||
x_0=x_start,
|
||||
t=t,
|
||||
noise=noise,
|
||||
model=self.model,
|
||||
model_kwargs={
|
||||
'cond':
|
||||
context,
|
||||
'mask':
|
||||
cont_mask,
|
||||
'gc_seg':
|
||||
gc_seg,
|
||||
'text_position_embeddings':
|
||||
self.text_position_embeddings.pos if hasattr(
|
||||
self.text_position_embeddings, 'pos') else None
|
||||
},
|
||||
**kwargs)
|
||||
loss = loss.mean()
|
||||
ret = {'loss': loss, 'probe_data': {'prompt': prompt}}
|
||||
return ret
|
||||
|
||||
@torch.no_grad()
|
||||
def forward_test(self,
|
||||
edit_image=[],
|
||||
edit_image_mask=[],
|
||||
image=None,
|
||||
image_mask=None,
|
||||
prompt=[],
|
||||
n_prompt=[],
|
||||
sampler='ddim',
|
||||
sample_steps=20,
|
||||
guide_scale=4.5,
|
||||
guide_rescale=0.5,
|
||||
log_num=-1,
|
||||
seed=2024,
|
||||
**kwargs):
|
||||
|
||||
assert check_list_of_list(prompt) and check_list_of_list(
|
||||
edit_image) and check_list_of_list(edit_image_mask)
|
||||
assert len(edit_image) == len(edit_image_mask) == len(prompt)
|
||||
assert self.cond_stage_model is not None
|
||||
# gc_seg is unused
|
||||
kwargs.pop('gc_seg', -1)
|
||||
# prepare data
|
||||
context, null_context = {}, {}
|
||||
|
||||
prompt, n_prompt, image, image_mask, edit_image, edit_image_mask = self.limit_batch_data(
|
||||
[prompt, n_prompt, image, image_mask, edit_image, edit_image_mask],
|
||||
log_num)
|
||||
g = torch.Generator(device=we.device_id)
|
||||
seed = seed if seed >= 0 else random.randint(0, 2**32 - 1)
|
||||
g.manual_seed(seed)
|
||||
n_prompt = copy.deepcopy(prompt)
|
||||
# only modify the last prompt to be zero
|
||||
for nn_p_id, nn_p in enumerate(n_prompt):
|
||||
if isinstance(nn_p, str):
|
||||
n_prompt[nn_p_id] = ['']
|
||||
elif isinstance(nn_p, list):
|
||||
n_prompt[nn_p_id][-1] = ''
|
||||
else:
|
||||
raise NotImplementedError
|
||||
# process image
|
||||
image = to_device(image)
|
||||
x = self.encode_first_stage(image, **kwargs)
|
||||
noise = [
|
||||
torch.empty(*i.shape, device=we.device_id).normal_(generator=g)
|
||||
for i in x
|
||||
]
|
||||
noise, x_shapes = pack_imagelist_into_tensor(noise)
|
||||
context['x_shapes'] = null_context['x_shapes'] = x_shapes
|
||||
|
||||
# process image mask
|
||||
image_mask = to_device(image_mask, strict=False)
|
||||
cond_mask = [self.interpolate_func(i) for i in image_mask
|
||||
] if image_mask is not None else [None] * len(image)
|
||||
context['x_mask'] = null_context['x_mask'] = cond_mask
|
||||
# process text
|
||||
# with torch.autocast(device_type="cuda", enabled=True, dtype=torch.bfloat16):
|
||||
prompt_ = [[pp] if isinstance(pp, str) else pp for pp in prompt]
|
||||
cont, cont_mask = getattr(self.cond_stage_model,
|
||||
'encode_list')(prompt_, return_mask=True)
|
||||
cont, cont_mask = self.cond_stage_embeddings(prompt, edit_image, cont,
|
||||
cont_mask)
|
||||
null_cont, null_cont_mask = getattr(self.cond_stage_model,
|
||||
'encode_list')(n_prompt,
|
||||
return_mask=True)
|
||||
null_cont, null_cont_mask = self.cond_stage_embeddings(
|
||||
prompt, edit_image, null_cont, null_cont_mask)
|
||||
context['crossattn'] = cont
|
||||
null_context['crossattn'] = null_cont
|
||||
|
||||
# processe edit image & edit image mask
|
||||
edit_image = [to_device(i, strict=False) for i in edit_image]
|
||||
edit_image_mask = [to_device(i, strict=False) for i in edit_image_mask]
|
||||
e_img, e_mask = [], []
|
||||
for u, m in zip(edit_image, edit_image_mask):
|
||||
if u is None:
|
||||
continue
|
||||
if m is None:
|
||||
m = [None] * len(u)
|
||||
e_img.append(self.encode_first_stage(u, **kwargs))
|
||||
e_mask.append([self.interpolate_func(i) for i in m])
|
||||
null_context['edit'] = context['edit'] = e_img
|
||||
null_context['edit_mask'] = context['edit_mask'] = e_mask
|
||||
|
||||
# process sample
|
||||
model = self.model_ema if self.use_ema and self.eval_ema else self.model
|
||||
embedding_context = model.no_sync if isinstance(model, torch.distributed.fsdp.FullyShardedDataParallel) \
|
||||
else nullcontext
|
||||
with embedding_context():
|
||||
samples = self.diffusion.sample(
|
||||
sampler=sampler,
|
||||
noise=noise,
|
||||
model=model,
|
||||
model_kwargs=[{
|
||||
'cond':
|
||||
context,
|
||||
'mask':
|
||||
cont_mask,
|
||||
'text_position_embeddings':
|
||||
self.text_position_embeddings.pos if hasattr(
|
||||
self.text_position_embeddings, 'pos') else None
|
||||
}, {
|
||||
'cond':
|
||||
null_context,
|
||||
'mask':
|
||||
null_cont_mask,
|
||||
'text_position_embeddings':
|
||||
self.text_position_embeddings.pos if hasattr(
|
||||
self.text_position_embeddings, 'pos') else None
|
||||
}] if guide_scale is not None and guide_scale > 1 else {
|
||||
'cond':
|
||||
context,
|
||||
'mask':
|
||||
cont_mask,
|
||||
'text_position_embeddings':
|
||||
self.text_position_embeddings.pos if hasattr(
|
||||
self.text_position_embeddings, 'pos') else None
|
||||
},
|
||||
steps=sample_steps,
|
||||
guide_scale=guide_scale,
|
||||
guide_rescale=guide_rescale,
|
||||
show_progress=True,
|
||||
**kwargs)
|
||||
|
||||
samples = unpack_tensor_into_imagelist(samples, x_shapes)
|
||||
x_samples = self.decode_first_stage(samples)
|
||||
outputs = list()
|
||||
for i in range(len(prompt)):
|
||||
rec_img = torch.clamp(
|
||||
(x_samples[i] + 1.0) / 2.0 + self.decoder_bias / 255,
|
||||
min=0.0,
|
||||
max=1.0)
|
||||
rec_img = rec_img.squeeze(0)
|
||||
edit_imgs, edit_img_masks = [], []
|
||||
if edit_image is not None and edit_image[i] is not None:
|
||||
if edit_image_mask[i] is None:
|
||||
edit_image_mask[i] = [None] * len(edit_image[i])
|
||||
for edit_img, edit_mask in zip(edit_image[i],
|
||||
edit_image_mask[i]):
|
||||
edit_img = torch.clamp((edit_img + 1.0) / 2.0,
|
||||
min=0.0,
|
||||
max=1.0)
|
||||
edit_imgs.append(edit_img.squeeze(0))
|
||||
if edit_mask is None:
|
||||
edit_mask = torch.ones_like(edit_img[[0], :, :])
|
||||
edit_img_masks.append(edit_mask)
|
||||
one_tup = {
|
||||
'reconstruct_image': rec_img,
|
||||
'instruction': prompt[i],
|
||||
'edit_image': edit_imgs if len(edit_imgs) > 0 else None,
|
||||
'edit_mask': edit_img_masks if len(edit_imgs) > 0 else None
|
||||
}
|
||||
if image is not None:
|
||||
if image_mask is None:
|
||||
image_mask = [None] * len(image)
|
||||
ori_img = torch.clamp((image[i] + 1.0) / 2.0, min=0.0, max=1.0)
|
||||
one_tup['target_image'] = ori_img.squeeze(0)
|
||||
one_tup['target_mask'] = image_mask[i] if image_mask[
|
||||
i] is not None else torch.ones_like(ori_img[[0], :, :])
|
||||
outputs.append(one_tup)
|
||||
return outputs
|
||||
|
||||
@staticmethod
|
||||
def get_config_template():
|
||||
return dict_to_yaml('MODEL',
|
||||
__class__.__name__,
|
||||
LatentDiffusionACE.para_dict,
|
||||
set_name=True)
|
||||
@@ -3,20 +3,15 @@
|
||||
import copy
|
||||
import numbers
|
||||
import random
|
||||
from collections import OrderedDict
|
||||
|
||||
import torch
|
||||
|
||||
from scepter.modules.model.network.diffusion.diffusion import GaussianDiffusion
|
||||
from scepter.modules.model.network.diffusion.schedules import noise_schedule
|
||||
from scepter.modules.model.network.ldm import LatentDiffusion
|
||||
from scepter.modules.model.network.train_module import TrainModule
|
||||
from scepter.modules.model.registry import (BACKBONES, EMBEDDERS, LOSSES,
|
||||
MODELS, TOKENIZERS)
|
||||
from scepter.modules.model.utils.basic_utils import count_params, default
|
||||
from scepter.modules.model.utils.basic_utils import count_params
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
|
||||
|
||||
def disabled_train(self, mode=True):
|
||||
|
||||
@@ -15,8 +15,8 @@ def build_model(cfg, registry, logger=None, *args, **kwargs):
|
||||
raise TypeError(f'Config must be type dict, got {type(cfg)}')
|
||||
if cfg.have('PRETRAINED_MODEL'):
|
||||
pretrain_cfg = cfg.PRETRAINED_MODEL
|
||||
if pretrain_cfg is not None and not isinstance(pretrain_cfg, (str)):
|
||||
raise TypeError('Pretrain parameter must be a string')
|
||||
if pretrain_cfg is not None and not isinstance(pretrain_cfg, (str, list)):
|
||||
raise TypeError('Pretrain parameter must be a string or list')
|
||||
else:
|
||||
pretrain_cfg = None
|
||||
|
||||
|
||||
@@ -1,13 +1,14 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import open_clip
|
||||
from transformers import CLIPTokenizer as transformer_clip_tokenizer
|
||||
|
||||
from scepter.modules.model.registry import TOKENIZERS
|
||||
from scepter.modules.model.tokenizer import BaseTokenizer
|
||||
from scepter.modules.model.tokenizer.tokenizer_component import (
|
||||
basic_clean, canonicalize, heavy_clean, whitespace_clean)
|
||||
basic_clean, canonicalize, whitespace_clean)
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.utils.file_system import FS
|
||||
from transformers import CLIPTokenizer as transformer_clip_tokenizer
|
||||
|
||||
|
||||
@TOKENIZERS.register_class()
|
||||
@@ -31,13 +32,16 @@ class HuggingfaceTokenizer(BaseTokenizer):
|
||||
super().__init__(cfg, logger=logger)
|
||||
self.pretrained_path = cfg.get('PRETRAINED_PATH', 'xlm-roberta-large')
|
||||
self.length = cfg.get('LENGTH', 77)
|
||||
self.clean = cfg.get('CLEAN', True)
|
||||
self.clean = cfg.get('CLEAN', 'whitespace')
|
||||
assert self.clean in (None, 'whitespace', 'lower', 'canonicalize')
|
||||
|
||||
# init tokenizer
|
||||
from transformers import AutoTokenizer
|
||||
with FS.get_dir_to_local_dir(self.pretrained_path) as local_path:
|
||||
self.tokenizer = AutoTokenizer.from_pretrained(local_path)
|
||||
self.vocab_size = len(self.tokenizer)
|
||||
|
||||
self.vocab_size = len(
|
||||
self.tokenizer) # self.vocab_size = self.tokenizer.vocab_size
|
||||
|
||||
# special tokens
|
||||
self.comma_token = self.tokenizer(',')['input_ids'][
|
||||
@@ -51,6 +55,7 @@ class HuggingfaceTokenizer(BaseTokenizer):
|
||||
|
||||
def __call__(self, sequence, **kwargs):
|
||||
# arguments
|
||||
return_mask = kwargs.pop('return_mask', False)
|
||||
_kwargs = {'return_tensors': 'pt'}
|
||||
if self.length is not None:
|
||||
_kwargs.update({
|
||||
@@ -64,9 +69,23 @@ class HuggingfaceTokenizer(BaseTokenizer):
|
||||
if isinstance(sequence, str):
|
||||
sequence = [sequence]
|
||||
if self.clean:
|
||||
sequence = [whitespace_clean(basic_clean(u)) for u in sequence]
|
||||
sequence = [self._clean(u) for u in sequence]
|
||||
tokens = self.tokenizer(sequence, **_kwargs)
|
||||
return tokens.input_ids
|
||||
|
||||
# output
|
||||
if return_mask:
|
||||
return tokens.input_ids, tokens.attention_mask
|
||||
else:
|
||||
return tokens.input_ids
|
||||
|
||||
def _clean(self, text):
|
||||
if self.clean == 'whitespace':
|
||||
text = whitespace_clean(basic_clean(text))
|
||||
elif self.clean == 'lower':
|
||||
text = whitespace_clean(basic_clean(text)).lower()
|
||||
elif self.clean == 'canonicalize':
|
||||
text = canonicalize(basic_clean(text))
|
||||
return text
|
||||
|
||||
@staticmethod
|
||||
def get_config_template():
|
||||
|
||||
@@ -2,6 +2,11 @@
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from inspect import isfunction
|
||||
|
||||
import torch
|
||||
from torch.nn.utils.rnn import pad_sequence
|
||||
|
||||
from scepter.modules.utils.distribute import we
|
||||
|
||||
|
||||
def exists(x):
|
||||
return x is not None
|
||||
@@ -45,3 +50,55 @@ def expand_dims_like(x, y):
|
||||
while x.dim() != y.dim():
|
||||
x = x.unsqueeze(-1)
|
||||
return x
|
||||
|
||||
|
||||
def unpack_tensor_into_imagelist(image_tensor, shapes):
|
||||
image_list = []
|
||||
for img, shape in zip(image_tensor, shapes):
|
||||
h, w = shape[0], shape[1]
|
||||
image_list.append(img[:, :h * w].view(1, -1, h, w))
|
||||
|
||||
return image_list
|
||||
|
||||
|
||||
def find_example(tensor_list, image_list):
|
||||
for i in tensor_list:
|
||||
if isinstance(i, torch.Tensor):
|
||||
return torch.zeros_like(i)
|
||||
for i in image_list:
|
||||
if isinstance(i, torch.Tensor):
|
||||
_, c, h, w = i.size()
|
||||
return torch.zeros_like(i.view(c, h * w).transpose(1, 0))
|
||||
return None
|
||||
|
||||
|
||||
def pack_imagelist_into_tensor_v2(image_list):
|
||||
# allow None
|
||||
example = None
|
||||
image_tensor, shapes = [], []
|
||||
for img in image_list:
|
||||
if img is None:
|
||||
example = find_example(image_tensor,
|
||||
image_list) if example is None else example
|
||||
image_tensor.append(example)
|
||||
shapes.append(None)
|
||||
continue
|
||||
_, c, h, w = img.size()
|
||||
image_tensor.append(img.view(c, h * w).transpose(1, 0)) # h*w, c
|
||||
shapes.append((h, w))
|
||||
|
||||
image_tensor = pad_sequence(image_tensor,
|
||||
batch_first=True).permute(0, 2, 1) # b, c, l
|
||||
return image_tensor, shapes
|
||||
|
||||
|
||||
def to_device(inputs, strict=True):
|
||||
if inputs is None:
|
||||
return None
|
||||
if strict:
|
||||
assert all(isinstance(i, torch.Tensor) for i in inputs)
|
||||
return [i.to(we.device_id) if i is not None else None for i in inputs]
|
||||
|
||||
|
||||
def check_list_of_list(ll):
|
||||
return isinstance(ll, list) and all(isinstance(i, list) for i in ll)
|
||||
|
||||
@@ -1,6 +1,7 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from scepter.modules.solver import hooks
|
||||
from scepter.modules.solver.ace_solver import ACESolver
|
||||
from scepter.modules.solver.base_solver import BaseSolver
|
||||
from scepter.modules.solver.diffusion_solver import LatentDiffusionSolver
|
||||
from scepter.modules.solver.train_val_solver import TrainValSolver
|
||||
|
||||
@@ -0,0 +1,146 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import numpy as np
|
||||
import torch
|
||||
from tqdm import tqdm
|
||||
|
||||
from scepter.modules.utils.data import transfer_data_to_cuda
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.probe import ProbeData
|
||||
|
||||
from .diffusion_solver import LatentDiffusionSolver
|
||||
from .registry import SOLVERS
|
||||
|
||||
|
||||
@SOLVERS.register_class()
|
||||
class ACESolver(LatentDiffusionSolver):
|
||||
def __init__(self, cfg, logger=None):
|
||||
super().__init__(cfg, logger=logger)
|
||||
self.log_train_num = cfg.get('LOG_TRAIN_NUM', -1)
|
||||
|
||||
def save_results(self, results):
|
||||
log_data, log_label = [], []
|
||||
for result in results:
|
||||
ret_images, ret_labels = [], []
|
||||
edit_image = result.get('edit_image', None)
|
||||
edit_mask = result.get('edit_mask', None)
|
||||
if edit_image is not None:
|
||||
for i, edit_img in enumerate(result['edit_image']):
|
||||
if edit_img is None:
|
||||
continue
|
||||
ret_images.append(
|
||||
(edit_img.permute(1, 2, 0).cpu().numpy() * 255).astype(
|
||||
np.uint8))
|
||||
ret_labels.append(f'edit_image{i}; ')
|
||||
if edit_mask is not None:
|
||||
ret_images.append(
|
||||
(edit_mask[i].permute(1, 2, 0).cpu().numpy() *
|
||||
255).astype(np.uint8))
|
||||
ret_labels.append(f'edit_mask{i}; ')
|
||||
|
||||
target_image = result.get('target_image', None)
|
||||
target_mask = result.get('target_mask', None)
|
||||
if target_image is not None:
|
||||
ret_images.append(
|
||||
(target_image.permute(1, 2, 0).cpu().numpy() * 255).astype(
|
||||
np.uint8))
|
||||
ret_labels.append('target_image; ')
|
||||
if target_mask is not None:
|
||||
ret_images.append(
|
||||
(target_mask.permute(1, 2, 0).cpu().numpy() *
|
||||
255).astype(np.uint8))
|
||||
ret_labels.append('target_mask; ')
|
||||
|
||||
reconstruct_image = result.get('reconstruct_image', None)
|
||||
if reconstruct_image is not None:
|
||||
ret_images.append(
|
||||
(reconstruct_image.permute(1, 2, 0).cpu().numpy() *
|
||||
255).astype(np.uint8))
|
||||
ret_labels.append(f"{result['instruction']}")
|
||||
log_data.append(ret_images)
|
||||
log_label.append(ret_labels)
|
||||
return log_data, log_label
|
||||
|
||||
@torch.no_grad()
|
||||
def run_eval(self):
|
||||
self.eval_mode()
|
||||
self.before_all_iter(self.hooks_dict[self._mode])
|
||||
all_results = []
|
||||
for batch_idx, batch_data in tqdm(
|
||||
enumerate(self.datas[self._mode].dataloader)):
|
||||
self.before_iter(self.hooks_dict[self._mode])
|
||||
if self.sample_args:
|
||||
batch_data.update(self.sample_args.get_lowercase_dict())
|
||||
with torch.autocast(device_type='cuda',
|
||||
enabled=self.use_amp,
|
||||
dtype=self.dtype):
|
||||
results = self.run_step_eval(transfer_data_to_cuda(batch_data),
|
||||
batch_idx,
|
||||
step=self.total_iter,
|
||||
rank=we.rank)
|
||||
all_results.extend(results)
|
||||
self.after_iter(self.hooks_dict[self._mode])
|
||||
log_data, log_label = self.save_results(all_results)
|
||||
self.register_probe({'eval_label': log_label})
|
||||
self.register_probe({
|
||||
'eval_image':
|
||||
ProbeData(log_data,
|
||||
is_image=True,
|
||||
build_html=True,
|
||||
build_label=log_label)
|
||||
})
|
||||
self.after_all_iter(self.hooks_dict[self._mode])
|
||||
|
||||
@torch.no_grad()
|
||||
def run_test(self):
|
||||
self.test_mode()
|
||||
self.before_all_iter(self.hooks_dict[self._mode])
|
||||
all_results = []
|
||||
for batch_idx, batch_data in tqdm(
|
||||
enumerate(self.datas[self._mode].dataloader)):
|
||||
self.before_iter(self.hooks_dict[self._mode])
|
||||
if self.sample_args:
|
||||
batch_data.update(self.sample_args.get_lowercase_dict())
|
||||
with torch.autocast(device_type='cuda',
|
||||
enabled=self.use_amp,
|
||||
dtype=self.dtype):
|
||||
results = self.run_step_eval(transfer_data_to_cuda(batch_data),
|
||||
batch_idx,
|
||||
step=self.total_iter,
|
||||
rank=we.rank)
|
||||
all_results.extend(results)
|
||||
self.after_iter(self.hooks_dict[self._mode])
|
||||
log_data, log_label = self.save_results(all_results)
|
||||
self.register_probe({'test_label': log_label})
|
||||
self.register_probe({
|
||||
'test_image':
|
||||
ProbeData(log_data,
|
||||
is_image=True,
|
||||
build_html=True,
|
||||
build_label=log_label)
|
||||
})
|
||||
|
||||
self.after_all_iter(self.hooks_dict[self._mode])
|
||||
|
||||
@property
|
||||
def probe_data(self):
|
||||
if not we.debug and self.mode == 'train':
|
||||
batch_data = transfer_data_to_cuda(
|
||||
self.current_batch_data[self.mode])
|
||||
self.eval_mode()
|
||||
with torch.autocast(device_type='cuda',
|
||||
enabled=self.use_amp,
|
||||
dtype=self.dtype):
|
||||
batch_data['log_num'] = self.log_train_num
|
||||
results = self.run_step_eval(batch_data)
|
||||
self.train_mode()
|
||||
log_data, log_label = self.save_results(results)
|
||||
self.register_probe({
|
||||
'train_image':
|
||||
ProbeData(log_data,
|
||||
is_image=True,
|
||||
build_html=True,
|
||||
build_label=log_label)
|
||||
})
|
||||
self.register_probe({'train_label': log_label})
|
||||
return super(LatentDiffusionSolver, self).probe_data
|
||||
@@ -8,6 +8,8 @@ from abc import ABCMeta
|
||||
from collections import OrderedDict, defaultdict
|
||||
|
||||
import torch
|
||||
from torch.nn.parallel import DistributedDataParallel
|
||||
|
||||
from scepter.modules.data.dataset import DATASETS
|
||||
from scepter.modules.model.base_model import BaseModel
|
||||
from scepter.modules.model.metric.registry import METRICS
|
||||
@@ -18,15 +20,14 @@ from scepter.modules.solver.hooks import HOOKS
|
||||
from scepter.modules.utils.config import Config, dict_to_yaml
|
||||
from scepter.modules.utils.data import transfer_data_to_cuda
|
||||
from scepter.modules.utils.directory import get_relative_folder, osp_path
|
||||
from scepter.modules.utils.distribute import (
|
||||
dist, gather_data, we, all_reduce,
|
||||
_serialize_to_tensor, broadcast, _unserialize_from_tensor,
|
||||
all_reduce, barrier)
|
||||
from scepter.modules.utils.distribute import (_serialize_to_tensor,
|
||||
_unserialize_from_tensor,
|
||||
all_reduce, barrier, broadcast,
|
||||
gather_data, we)
|
||||
from scepter.modules.utils.file_system import FS
|
||||
from scepter.modules.utils.logger import get_logger, init_logger
|
||||
from scepter.modules.utils.probe import (ProbeData, merge_gathered_probe,
|
||||
register_data)
|
||||
from torch.nn.parallel import DistributedDataParallel
|
||||
|
||||
try:
|
||||
import pytorch_lightning as pl
|
||||
@@ -187,6 +188,7 @@ try:
|
||||
except Exception as e:
|
||||
warnings.warn(f'{e}')
|
||||
|
||||
|
||||
def async_str(text):
|
||||
broadcast_size = torch.zeros(1, dtype=torch.long).to(we.device_id)
|
||||
if we.rank == 0:
|
||||
@@ -196,7 +198,8 @@ def async_str(text):
|
||||
broadcast(text_tensor, src=0)
|
||||
else:
|
||||
broadcast(broadcast_size, src=0)
|
||||
text_tensor = torch.empty((broadcast_size[0],), dtype=torch.uint8).to(we.device_id)
|
||||
text_tensor = torch.empty((broadcast_size[0], ),
|
||||
dtype=torch.uint8).to(we.device_id)
|
||||
broadcast(text_tensor, src=0)
|
||||
text = _unserialize_from_tensor(text_tensor)
|
||||
return text
|
||||
@@ -271,8 +274,8 @@ class BaseSolver(object, metaclass=ABCMeta):
|
||||
self.pl_dir = self.work_dir
|
||||
self.log_file = osp_path(self.work_dir, cfg.LOG_FILE)
|
||||
self.optimizer, self.lr_scheduler = None, None
|
||||
self.resume_from: str = cfg.get("RESUME_FROM", None)
|
||||
self.max_epochs: int = cfg.get("MAX_EPOCHS", -1)
|
||||
self.resume_from: str = cfg.get('RESUME_FROM', None)
|
||||
self.max_epochs: int = cfg.get('MAX_EPOCHS', -1)
|
||||
self.use_pl = we.use_pl
|
||||
self.train_precision = self.cfg.get('TRAIN_PRECISION', 32)
|
||||
self._mode_set = set()
|
||||
@@ -284,7 +287,7 @@ class BaseSolver(object, metaclass=ABCMeta):
|
||||
if not self.use_pl:
|
||||
world_size = we.world_size
|
||||
if world_size > 1:
|
||||
self._num_folds: int = cfg.get("NUM_FOLDS", 1)
|
||||
self._num_folds: int = cfg.get('NUM_FOLDS', 1)
|
||||
if cfg.have('MODE'):
|
||||
self._mode_set.add(cfg.MODE)
|
||||
self._mode = cfg.MODE
|
||||
@@ -765,17 +768,21 @@ class BaseSolver(object, metaclass=ABCMeta):
|
||||
save_folder = pre_save_paras['save_folder']
|
||||
save_probe_prefix = pre_save_paras['save_probe_prefix']
|
||||
step = pre_save_paras['step']
|
||||
save_image_postfix = pre_save_paras.get('save_image_postfix', 'jpg')
|
||||
save_video_postfix = pre_save_paras.get('save_video_postfix', 'mp4')
|
||||
save_image_postfix = pre_save_paras.get('save_image_postfix',
|
||||
'jpg')
|
||||
save_video_postfix = pre_save_paras.get('save_video_postfix',
|
||||
'mp4')
|
||||
for k, v in self.collect_probe.items():
|
||||
if save_probe_prefix is not None:
|
||||
ret_prefix = os.path.join(save_folder, save_probe_prefix)
|
||||
else:
|
||||
ret_prefix = os.path.join(save_folder, k.replace('/', '_') + f'_step_{step}')
|
||||
v.presave(prefix = ret_prefix,
|
||||
image_postfix = save_image_postfix,
|
||||
video_postfix = save_video_postfix,
|
||||
rank = we.rank)
|
||||
ret_prefix = os.path.join(
|
||||
save_folder,
|
||||
k.replace('/', '_') + f'_step_{step}')
|
||||
v.presave(prefix=ret_prefix,
|
||||
image_postfix=save_image_postfix,
|
||||
video_postfix=save_video_postfix,
|
||||
rank=we.rank)
|
||||
gather_probe_data = gather_data(self._probe_data[self.mode])
|
||||
_dist_data_list = gather_data([self._dist_data[self.mode] or {}])
|
||||
if not we.rank == 0:
|
||||
@@ -877,7 +884,7 @@ class BaseSolver(object, metaclass=ABCMeta):
|
||||
if we.is_distributed:
|
||||
value = value.data.clone()
|
||||
all_reduce(value, group=we.data_parallel_group)
|
||||
value = value/we.data_group_world_size
|
||||
value = value / we.data_group_world_size
|
||||
ret[key] = value
|
||||
else:
|
||||
ret[key] = value
|
||||
|
||||
@@ -10,23 +10,24 @@ from functools import partial
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from torch.distributed.fsdp import FullStateDictConfig
|
||||
from torch.distributed.fsdp import FullyShardedDataParallel as FSDP
|
||||
from torch.distributed.fsdp import (MixedPrecision, ShardingStrategy,
|
||||
StateDictType)
|
||||
from torch.distributed.fsdp.wrap import lambda_auto_wrap_policy
|
||||
from torch.nn.parallel import DistributedDataParallel
|
||||
from tqdm import tqdm
|
||||
|
||||
from scepter.modules.data.dataset import DATASETS
|
||||
from scepter.modules.opt.lr_schedulers import LR_SCHEDULERS
|
||||
from scepter.modules.opt.optimizers import OPTIMIZERS
|
||||
from scepter.modules.solver import BaseSolver
|
||||
from scepter.modules.solver.registry import SOLVERS
|
||||
from scepter.modules.utils.config import Config, dict_to_yaml
|
||||
from scepter.modules.utils.data import transfer_data_to_cuda
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.probe import ProbeData
|
||||
from torch.distributed.fsdp import FullStateDictConfig
|
||||
from torch.distributed.fsdp import FullyShardedDataParallel as FSDP
|
||||
from torch.distributed.fsdp import (MixedPrecision, ShardingStrategy,
|
||||
StateDictType)
|
||||
from torch.distributed.fsdp.wrap import (lambda_auto_wrap_policy,
|
||||
size_based_auto_wrap_policy)
|
||||
from torch.nn.parallel import DistributedDataParallel
|
||||
from tqdm import tqdm
|
||||
|
||||
from .base_solver import BaseSolver
|
||||
|
||||
sharding_strategy_map = {
|
||||
'full_shard': ShardingStrategy.FULL_SHARD,
|
||||
@@ -40,13 +41,14 @@ def shard_model(model,
|
||||
param_dtype=torch.bfloat16,
|
||||
reduce_dtype=torch.float32,
|
||||
buffer_dtype=torch.float32,
|
||||
fsdp_group = ['blocks'],
|
||||
fsdp_group=['blocks'],
|
||||
sharding_strategy=ShardingStrategy.FULL_SHARD,
|
||||
sync_module_states=False):
|
||||
wrap_modules = []
|
||||
for module_name in fsdp_group:
|
||||
if hasattr(model, module_name):
|
||||
if isinstance(getattr(model, module_name), (list, tuple, nn.ModuleList)):
|
||||
if isinstance(getattr(model, module_name),
|
||||
(list, tuple, nn.ModuleList)):
|
||||
wrap_modules.extend([m for m in getattr(model, module_name)])
|
||||
else:
|
||||
wrap_modules.extend([getattr(model, module_name)])
|
||||
@@ -209,7 +211,7 @@ class LatentDiffusionSolver(BaseSolver):
|
||||
self.sample_args = cfg.get('SAMPLE_ARGS', None)
|
||||
self.tuner_cfg = cfg.get('TUNER', None)
|
||||
self.freeze_cfg = cfg.get('FREEZE', None)
|
||||
self.log_train_num = cfg.get("LOG_TRAIN_NUM", -1)
|
||||
self.log_train_num = cfg.get('LOG_TRAIN_NUM', -1)
|
||||
|
||||
def set_up(self):
|
||||
self.construct_data()
|
||||
@@ -285,11 +287,10 @@ class LatentDiffusionSolver(BaseSolver):
|
||||
from fairscale.nn.data_parallel import ShardedDataParallel
|
||||
from fairscale.optim.oss import OSS
|
||||
if hasattr(self.model, 'ignored_parameters'):
|
||||
train_params, ignored_params = self.model.parameters(
|
||||
train_params, _ = self.model.parameters(
|
||||
), self.model.ignored_parameters()
|
||||
else:
|
||||
train_params, ignored_params = self.model.parameters(
|
||||
), None
|
||||
train_params, _ = self.model.parameters(), None
|
||||
self.optimizer = OSS(params=train_params,
|
||||
optim=torch.optim.AdamW,
|
||||
lr=self.cfg.OPTIMIZER.LEARNING_RATE)
|
||||
@@ -302,16 +303,18 @@ class LatentDiffusionSolver(BaseSolver):
|
||||
sub_module = get_module(self.model, module)
|
||||
if sub_module is not None:
|
||||
sub_module = shard_model(
|
||||
sub_module,
|
||||
device_id=we.device_id,
|
||||
param_dtype=self.dtype,
|
||||
reduce_dtype=self.reduce_dtype,
|
||||
buffer_dtype=self.buffer_dtype,
|
||||
sharding_strategy=sharding_strategy_map[self.model_shard],
|
||||
sync_module_states=True)
|
||||
sub_module,
|
||||
device_id=we.device_id,
|
||||
param_dtype=self.dtype,
|
||||
reduce_dtype=self.reduce_dtype,
|
||||
buffer_dtype=self.buffer_dtype,
|
||||
sharding_strategy=sharding_strategy_map[
|
||||
self.model_shard],
|
||||
sync_module_states=True)
|
||||
set_module(self.model, module, sub_module)
|
||||
elif isinstance(module, (dict, Config)):
|
||||
sub_module = get_module(self.model, module["MODULE"])
|
||||
sub_module = get_module(self.model,
|
||||
module['MODULE'])
|
||||
if sub_module is not None:
|
||||
sub_module = shard_model(
|
||||
sub_module,
|
||||
@@ -319,10 +322,13 @@ class LatentDiffusionSolver(BaseSolver):
|
||||
param_dtype=self.dtype,
|
||||
reduce_dtype=self.reduce_dtype,
|
||||
buffer_dtype=self.buffer_dtype,
|
||||
fsdp_group=module.get("FSDP_GROUP", ["blocks"]),
|
||||
sharding_strategy=sharding_strategy_map[self.model_shard],
|
||||
fsdp_group=module.get(
|
||||
'FSDP_GROUP', ['blocks']),
|
||||
sharding_strategy=sharding_strategy_map[
|
||||
self.model_shard],
|
||||
sync_module_states=True)
|
||||
set_module(self.model, module["MODULE"], sub_module)
|
||||
set_module(self.model, module['MODULE'],
|
||||
sub_module)
|
||||
else:
|
||||
self.logger.warning(
|
||||
'FSDP_SHARD_MODULES is None, which means wraping the whold model as the '
|
||||
@@ -390,6 +396,7 @@ class LatentDiffusionSolver(BaseSolver):
|
||||
else:
|
||||
self.scaler = None
|
||||
self.logger.info(self.model)
|
||||
|
||||
def load_checkpoint(self, checkpoint: dict):
|
||||
"""
|
||||
Load checkpoint function
|
||||
@@ -443,10 +450,10 @@ class LatentDiffusionSolver(BaseSolver):
|
||||
f'Load checkpoint for optimizer {module}.')
|
||||
else:
|
||||
self.optimizer.load_state_dict(checkpoint['optimizer'])
|
||||
self.logger.info(f'Load checkpoint for optimizer.')
|
||||
self.logger.info('Load checkpoint for optimizer.')
|
||||
if 'scaler' in checkpoint and self.scaler:
|
||||
self.scaler.load_state_dict(checkpoint['scaler'])
|
||||
self.logger.info(f'Load checkpoint for scaler.')
|
||||
self.logger.info('Load checkpoint for scaler.')
|
||||
self.logger.info('Load checkpoint finished.')
|
||||
|
||||
def save_checkpoint(self) -> dict:
|
||||
@@ -498,7 +505,7 @@ class LatentDiffusionSolver(BaseSolver):
|
||||
model = self.model
|
||||
if self.save_modules is not None:
|
||||
for module in self.save_modules:
|
||||
current_module = get_module(self.model, module)
|
||||
current_module = get_module(model, module)
|
||||
if current_module is not None:
|
||||
ckpt['model'][module] = current_module.state_dict()
|
||||
else:
|
||||
@@ -510,7 +517,7 @@ class LatentDiffusionSolver(BaseSolver):
|
||||
model = self.model
|
||||
if self.save_modules is not None:
|
||||
for module in self.save_modules:
|
||||
current_module = get_module(self.model, module)
|
||||
current_module = get_module(model, module)
|
||||
if current_module is not None:
|
||||
ckpt['model'][module] = current_module.state_dict()
|
||||
else:
|
||||
@@ -624,12 +631,12 @@ class LatentDiffusionSolver(BaseSolver):
|
||||
# the inference image use
|
||||
ret_images, ret_labels = [], []
|
||||
if 'hint' in result:
|
||||
ret_images.append((result['hint'][:result['image'].shape[0]].permute(1, 2, 0).cpu().numpy() *
|
||||
255).astype(np.uint8))
|
||||
ret_labels.append(f"Control Image")
|
||||
ret_images.append(
|
||||
(result['image'].permute(1, 2, 0).cpu().numpy() *
|
||||
255).astype(np.uint8))
|
||||
ret_images.append(
|
||||
(result['hint'][:result['image'].shape[0]].permute(
|
||||
1, 2, 0).cpu().numpy() * 255).astype(np.uint8))
|
||||
ret_labels.append('Control Image')
|
||||
ret_images.append((result['image'].permute(1, 2, 0).cpu().numpy() *
|
||||
255).astype(np.uint8))
|
||||
ret_labels.append(result['prompt'] +
|
||||
" <font color='red'> |NegPrompt| </font> " +
|
||||
result['n_prompt'])
|
||||
@@ -671,15 +678,15 @@ class LatentDiffusionSolver(BaseSolver):
|
||||
# the inference image use
|
||||
ret_images, ret_labels = [], []
|
||||
if 'hint' in result:
|
||||
ret_images.append((result['hint'][:result['image'].shape[0]].permute(1, 2, 0).cpu().numpy() *
|
||||
255).astype(np.uint8))
|
||||
ret_labels.append(f"Control Image")
|
||||
ret_images.append(
|
||||
(result['image'].permute(1, 2, 0).cpu().numpy() *
|
||||
255).astype(np.uint8))
|
||||
ret_images.append(
|
||||
(result['hint'][:result['image'].shape[0]].permute(
|
||||
1, 2, 0).cpu().numpy() * 255).astype(np.uint8))
|
||||
ret_labels.append('Control Image')
|
||||
ret_images.append((result['image'].permute(1, 2, 0).cpu().numpy() *
|
||||
255).astype(np.uint8))
|
||||
ret_labels.append(result['prompt'] +
|
||||
" <font color='red'> |NegPrompt| </font> " +
|
||||
result['n_prompt'])
|
||||
" <font color='red'> |NegPrompt| </font> " +
|
||||
result['n_prompt'])
|
||||
log_data.append(ret_images)
|
||||
log_label.append(ret_labels)
|
||||
ori_label.append(result['prompt'])
|
||||
@@ -710,7 +717,9 @@ class LatentDiffusionSolver(BaseSolver):
|
||||
from swift import Swift
|
||||
model = Swift.prepare_model(self.model, config=swift_cfg_dict)
|
||||
|
||||
self.logger.info([(key, param.shape) for key, param in model.named_parameters() if param.requires_grad])
|
||||
self.logger.info([(key, param.shape)
|
||||
for key, param in model.named_parameters()
|
||||
if param.requires_grad])
|
||||
return model
|
||||
|
||||
def freeze(self, freeze_cfg, model=None):
|
||||
@@ -772,7 +781,9 @@ class LatentDiffusionSolver(BaseSolver):
|
||||
for name, param in freeze_model.named_parameters():
|
||||
if re.match(train_part, name):
|
||||
param.requires_grad = True
|
||||
self.logger.info([(key, param.shape) for key, param in freeze_model.named_parameters() if param.requires_grad])
|
||||
self.logger.info([(key, param.shape)
|
||||
for key, param in freeze_model.named_parameters()
|
||||
if param.requires_grad])
|
||||
return model
|
||||
|
||||
@torch.no_grad()
|
||||
@@ -815,30 +826,37 @@ class LatentDiffusionSolver(BaseSolver):
|
||||
@property
|
||||
def probe_data(self):
|
||||
if not we.debug and self.mode == 'train':
|
||||
batch_data = transfer_data_to_cuda(self.current_batch_data[self.mode])
|
||||
batch_data = transfer_data_to_cuda(
|
||||
self.current_batch_data[self.mode])
|
||||
self.eval_mode()
|
||||
with torch.autocast(device_type='cuda',
|
||||
enabled=self.use_amp,
|
||||
dtype=self.dtype):
|
||||
batch_data['log_num'] = self.log_train_num
|
||||
results = self.run_step_eval(batch_data)
|
||||
images = batch_data['image'] if 'image' in batch_data else [None] * len(results)
|
||||
images = batch_data['image'] if 'image' in batch_data else [
|
||||
None
|
||||
] * len(results)
|
||||
self.train_mode()
|
||||
log_data, log_label = [], []
|
||||
for result, image in zip(results, images):
|
||||
ret_images, ret_labels = [], []
|
||||
if 'hint' in result:
|
||||
ret_images.append((result['hint'][:result['image'].shape[0]].permute(1, 2, 0).cpu().numpy() *
|
||||
255).astype(np.uint8))
|
||||
ret_images.append(
|
||||
(result['hint'][:result['image'].shape[0]].permute(
|
||||
1, 2, 0).cpu().numpy() * 255).astype(np.uint8))
|
||||
if image is not None:
|
||||
image = torch.clamp((image + 1.0) / 2.0, min=0.0, max=1.0)
|
||||
ret_images.append((image.permute(1, 2, 0).cpu().numpy() * 255).astype(np.uint8))
|
||||
ret_labels.append(f'target image')
|
||||
ret_images.append((image.permute(1, 2, 0).cpu().numpy() *
|
||||
255).astype(np.uint8))
|
||||
ret_labels.append('target image')
|
||||
|
||||
ret_images.append((result['image'].permute(1, 2, 0).cpu().numpy() * 255).astype(np.uint8))
|
||||
ret_labels.append(result['prompt']
|
||||
+ " <font color='red'> |NegPrompt| </font> "
|
||||
+ result['n_prompt'])
|
||||
ret_images.append(
|
||||
(result['image'].permute(1, 2, 0).cpu().numpy() *
|
||||
255).astype(np.uint8))
|
||||
ret_labels.append(result['prompt'] +
|
||||
" <font color='red'> |NegPrompt| </font> " +
|
||||
result['n_prompt'])
|
||||
log_data.append(ret_images)
|
||||
log_label.append(ret_labels)
|
||||
self.register_probe({
|
||||
@@ -929,4 +947,4 @@ class LatentDiffusionSolver(BaseSolver):
|
||||
logger.info(
|
||||
f'Load ema frozen params {ema_param_numel} / {all_param_numel} = '
|
||||
f'{ema_param_numel / all_param_numel:.2%}, '
|
||||
f'frozen part: {ema_param_dict}.')
|
||||
f'frozen part: {ema_param_dict}.')
|
||||
|
||||
@@ -4,13 +4,12 @@ import os
|
||||
import warnings
|
||||
|
||||
import torch
|
||||
from scepter.modules.utils.file_system import FS
|
||||
|
||||
from scepter.modules.utils.distribute import we
|
||||
|
||||
from scepter.modules.solver.hooks.hook import Hook
|
||||
from scepter.modules.solver.hooks.registry import HOOKS
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
|
||||
_DEFAULT_BACKWARD_PRIORITY = 0
|
||||
|
||||
@@ -87,15 +86,21 @@ class BackwardHook(Hook):
|
||||
os.makedirs(self._local_log_dir, exist_ok=True)
|
||||
if self.do_profile:
|
||||
self.prof = torch.profiler.profile(
|
||||
schedule=torch.profiler.schedule(wait=self.wait, warmup=self.warmup, active=self.active, repeat=self.repeat),
|
||||
on_trace_ready=torch.profiler.tensorboard_trace_handler(self._local_log_dir),
|
||||
schedule=torch.profiler.schedule(wait=self.wait,
|
||||
warmup=self.warmup,
|
||||
active=self.active,
|
||||
repeat=self.repeat),
|
||||
on_trace_ready=torch.profiler.tensorboard_trace_handler(
|
||||
self._local_log_dir),
|
||||
record_shapes=True,
|
||||
with_stack=True)
|
||||
self.prof.start()
|
||||
solver.logger.info(f'Profiler start ...')
|
||||
solver.logger.info('Profiler start ...')
|
||||
solver.logger.info(f'Profiler: save to {self.log_dir}')
|
||||
|
||||
def profile(self, solver):
|
||||
if self.prof is None: return
|
||||
if self.prof is None:
|
||||
return
|
||||
if we.rank == 0 and self.do_profile:
|
||||
if self.profile_step < self.wait + self.warmup + self.active:
|
||||
self.prof.step()
|
||||
@@ -103,8 +108,10 @@ class BackwardHook(Hook):
|
||||
else:
|
||||
self.prof.stop()
|
||||
self.do_profile = False
|
||||
solver.logger.info(f'Profiler stop after {self.profile_step} steps')
|
||||
solver.logger.info(
|
||||
f'Profiler stop after {self.profile_step} steps')
|
||||
FS.put_dir_from_local_dir(self._local_log_dir, self.log_dir)
|
||||
|
||||
def grad_clip(self, parameters):
|
||||
torch.nn.utils.clip_grad_norm_(parameters=parameters,
|
||||
max_norm=self.gradient_clip,
|
||||
@@ -118,7 +125,8 @@ class BackwardHook(Hook):
|
||||
)
|
||||
return
|
||||
if solver.scaler is not None:
|
||||
solver.scaler.scale(solver.loss/self.accumulate_step).backward()
|
||||
solver.scaler.scale(solver.loss /
|
||||
self.accumulate_step).backward()
|
||||
if self.gradient_clip > 0:
|
||||
solver.scaler.unscale_(solver.optimizer)
|
||||
self.grad_clip(solver.train_parameters())
|
||||
@@ -131,7 +139,7 @@ class BackwardHook(Hook):
|
||||
solver.scaler.update()
|
||||
solver.optimizer.zero_grad()
|
||||
else:
|
||||
(solver.loss/self.accumulate_step).backward()
|
||||
(solver.loss / self.accumulate_step).backward()
|
||||
if self.gradient_clip > 0:
|
||||
self.grad_clip(solver.train_parameters())
|
||||
self.current_step += 1
|
||||
|
||||
@@ -7,6 +7,7 @@ import cv2
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import Image, ImageFile
|
||||
|
||||
from scepter.modules.transform.registry import TRANSFORMS
|
||||
from scepter.modules.utils.config import dict_to_yaml
|
||||
from scepter.modules.utils.distribute import we
|
||||
@@ -15,18 +16,18 @@ from scepter.modules.utils.file_system import DATA_FS as FS
|
||||
ImageFile.LOAD_TRUNCATED_IMAGES = True
|
||||
|
||||
|
||||
def pillow_convert(image, rgb_order):
|
||||
if image.mode != rgb_order:
|
||||
def pillow_convert(image, cvt_type):
|
||||
if image.mode != cvt_type:
|
||||
if image.mode == 'P':
|
||||
image = image.convert(f'{rgb_order}A')
|
||||
if image.mode == f'{rgb_order}A':
|
||||
bg = Image.new(rgb_order,
|
||||
image = image.convert(f'{cvt_type}A')
|
||||
if image.mode == f'{cvt_type}A':
|
||||
bg = Image.new(cvt_type,
|
||||
size=(image.width, image.height),
|
||||
color=(255, 255, 255))
|
||||
bg.paste(image, (0, 0), mask=image)
|
||||
image = bg
|
||||
else:
|
||||
image = image.convert('RGB')
|
||||
image = image.convert(cvt_type)
|
||||
return image
|
||||
|
||||
|
||||
|
||||
@@ -201,6 +201,11 @@ def broadcast(tensor, src, group=None, **kwargs):
|
||||
return dist.broadcast(tensor, src, group, **kwargs)
|
||||
|
||||
|
||||
def broadcast_object_list(object_list, src, group=None, **kwargs):
|
||||
if we.is_distributed:
|
||||
return dist.broadcast_object_list(object_list, src, group, **kwargs)
|
||||
|
||||
|
||||
def barrier():
|
||||
if we.is_distributed:
|
||||
dist.barrier()
|
||||
|
||||
+145
-78
@@ -1,7 +1,6 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import copy
|
||||
import json
|
||||
import os.path
|
||||
from io import BytesIO
|
||||
from numbers import Number
|
||||
@@ -9,6 +8,7 @@ from numbers import Number
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import Image
|
||||
|
||||
from scepter.modules.utils.file_system import FS
|
||||
|
||||
|
||||
@@ -76,6 +76,7 @@ def merge_gathered_probe(all_gathered_data):
|
||||
all_gathered_data[key] = ProbeData(
|
||||
new_data,
|
||||
is_image=ret_data.is_image,
|
||||
is_video=ret_data.is_video,
|
||||
build_html=ret_data.build_html,
|
||||
build_label=ret_data.build_label,
|
||||
view_distribute=ret_data.view_distribute,
|
||||
@@ -96,6 +97,7 @@ def merge_gathered_probe(all_gathered_data):
|
||||
all_gathered_data[key] = ProbeData(
|
||||
ret_data.data,
|
||||
is_image=ret_data.is_image,
|
||||
is_video=ret_data.is_video,
|
||||
build_html=ret_data.build_html,
|
||||
build_label=ret_data.build_label,
|
||||
view_distribute=ret_data.view_distribute,
|
||||
@@ -106,7 +108,7 @@ def merge_gathered_probe(all_gathered_data):
|
||||
|
||||
|
||||
class MediaHandler():
|
||||
def __init__(self, batch_size = 10):
|
||||
def __init__(self, batch_size=10):
|
||||
self.file_list = []
|
||||
self.target_path_list = []
|
||||
self.target_status = {}
|
||||
@@ -116,20 +118,27 @@ class MediaHandler():
|
||||
self.file_list.append(source_file)
|
||||
self.target_path_list.append(target_path)
|
||||
if len(self.file_list) > 2 * self.batch_size:
|
||||
generator = FS.put_batch_objects_to(self.file_list, self.target_path_list, batch_size=self.batch_size)
|
||||
generator = FS.put_batch_objects_to(self.file_list,
|
||||
self.target_path_list,
|
||||
batch_size=self.batch_size)
|
||||
for local_path, target_path, flg in generator:
|
||||
self.target_status[target_path] = flg
|
||||
self.file_list.clear()
|
||||
self.target_path_list.clear()
|
||||
|
||||
def sync(self):
|
||||
if len(self.file_list) > 0:
|
||||
if len(self.file_list) > 4 * self.batch_size:
|
||||
generator = FS.put_batch_objects_to(self.file_list, self.target_path_list, batch_size=self.batch_size)
|
||||
generator = FS.put_batch_objects_to(self.file_list,
|
||||
self.target_path_list,
|
||||
batch_size=self.batch_size)
|
||||
for local_path, target_path, flg in generator:
|
||||
self.target_status[target_path] = flg
|
||||
else:
|
||||
for file_, target_path in zip(self.file_list, self.target_path_list):
|
||||
self.target_status[target_path] = FS.put_object(file_.getvalue(), target_path)
|
||||
for file_, target_path in zip(self.file_list,
|
||||
self.target_path_list):
|
||||
self.target_status[target_path] = FS.put_object(
|
||||
file_.getvalue(), target_path)
|
||||
self.file_list.clear()
|
||||
self.target_path_list.clear()
|
||||
|
||||
@@ -148,7 +157,7 @@ class ProbeData():
|
||||
build_html=False,
|
||||
build_label=None,
|
||||
view_distribute=False,
|
||||
is_presave = False):
|
||||
is_presave=False):
|
||||
''' Probe Data Initialize.
|
||||
We only support basic types such as [torch.Tensor, numpy.ndarray, number, str],
|
||||
or [dict, list] of [dict, list,
|
||||
@@ -243,7 +252,8 @@ class ProbeData():
|
||||
for v_idx, v_v in enumerate(v):
|
||||
if not check_legal_type(v_v):
|
||||
if isinstance(v_v, torch.Tensor):
|
||||
data[idx][v_idx] = v_v.detach().cpu().numpy()
|
||||
data[idx][v_idx] = v_v.detach().cpu(
|
||||
).numpy()
|
||||
self.basic_type = False
|
||||
elif isinstance(v_v, np.ndarray):
|
||||
data[idx][v_idx] = v_v
|
||||
@@ -296,25 +306,33 @@ class ProbeData():
|
||||
if extension.lower() in ['png']:
|
||||
return 'PNG'
|
||||
return 'JPEG'
|
||||
def save_one_video(self, file_path, videos, fps = 8):
|
||||
|
||||
def save_one_video(self, file_path, videos, fps=8):
|
||||
# write video
|
||||
import imageio
|
||||
try:
|
||||
writer = imageio.get_writer(file_path, fps=fps, format=".mp4", codec='libx264', quality=8)
|
||||
writer = imageio.get_writer(file_path,
|
||||
fps=fps,
|
||||
format='.mp4',
|
||||
codec='libx264',
|
||||
quality=8)
|
||||
for frame in videos:
|
||||
writer.append_data(frame)
|
||||
writer.close()
|
||||
return True
|
||||
except:
|
||||
except Exception:
|
||||
return False
|
||||
|
||||
|
||||
def save_video(self, file_prefix, videos, video_postfix, fps = 8, rank = 0):
|
||||
def save_video(self, file_prefix, videos, video_postfix, fps=8, rank=0):
|
||||
if isinstance(videos, list):
|
||||
for video in videos:
|
||||
if isinstance(video, list):
|
||||
raise f"Only surpport one layer nested list."
|
||||
return [self.save_video(file_prefix + f'_{rank}_{idx}', v, video_postfix, fps) for idx, v in enumerate(videos)]
|
||||
raise 'Only surpport one layer nested list.'
|
||||
return [
|
||||
self.save_video(file_prefix + f'_{rank}_{idx}', v,
|
||||
video_postfix, fps)
|
||||
for idx, v in enumerate(videos)
|
||||
]
|
||||
np_shape = videos.shape
|
||||
# 4D
|
||||
shape_str = '_'.join([str(v) for v in np_shape])
|
||||
@@ -326,15 +344,22 @@ class ProbeData():
|
||||
file_list = []
|
||||
for idx in range(np_shape[0]):
|
||||
if videos[idx].shape[0] > 1:
|
||||
file_path = os.path.join(file_prefix, f'probe_{rank}_{idx}_[{shape_str}].{video_postfix}')
|
||||
file_path = os.path.join(
|
||||
file_prefix,
|
||||
f'probe_{rank}_{idx}_[{shape_str}].{video_postfix}'
|
||||
)
|
||||
byio = BytesIO()
|
||||
is_suc = self.save_one_video(byio, videos[idx], fps)
|
||||
if not is_suc:
|
||||
byio.write(b"")
|
||||
byio.write(b'')
|
||||
else:
|
||||
file_path = os.path.join(file_prefix, f'probe_{rank}_{idx}_[{shape_str}].{self.image_postfix}')
|
||||
file_path = os.path.join(
|
||||
file_prefix,
|
||||
f'probe_{rank}_{idx}_[{shape_str}].{self.image_postfix}'
|
||||
)
|
||||
byio = BytesIO()
|
||||
Image.fromarray(videos[idx][0]).save(byio, self.get_format(self.image_postfix))
|
||||
Image.fromarray(videos[idx][0]).save(
|
||||
byio, self.get_format(self.image_postfix))
|
||||
self.media_handler.append(byio, file_path)
|
||||
file_list.append(file_path)
|
||||
return file_list
|
||||
@@ -349,25 +374,32 @@ class ProbeData():
|
||||
byio = BytesIO()
|
||||
is_suc = self.save_one_video(byio, videos, fps)
|
||||
if not is_suc:
|
||||
byio.write(b"")
|
||||
byio.write(b'')
|
||||
else:
|
||||
file_path = file_prefix + f'_probe_{rank}_[{shape_str}].{self.image_postfix}'
|
||||
byio = BytesIO()
|
||||
Image.fromarray(videos[0]).save(byio, self.get_format(self.image_postfix))
|
||||
Image.fromarray(videos[0]).save(
|
||||
byio, self.get_format(self.image_postfix))
|
||||
self.media_handler.append(byio, file_path)
|
||||
return file_path
|
||||
else:
|
||||
videos = videos.reshape(list(videos.shape) + [1])
|
||||
return self.save_video(file_prefix, videos, video_postfix, fps = fps)
|
||||
return self.save_video(file_prefix,
|
||||
videos,
|
||||
video_postfix,
|
||||
fps=fps)
|
||||
else:
|
||||
raise f"Ensure your data's dim is BFWHC or FWHC, and channel is 1 or 3 for {file_prefix}"
|
||||
|
||||
def save_image(self, file_prefix, images, image_postfix, rank = 0):
|
||||
def save_image(self, file_prefix, images, image_postfix, rank=0):
|
||||
if isinstance(images, list):
|
||||
for image in images:
|
||||
if isinstance(image, list):
|
||||
raise f"Only surpport one layer nested list."
|
||||
return [self.save_image(file_prefix + f'_{rank}_{idx}', v, image_postfix) for idx, v in enumerate(images)]
|
||||
raise TypeError('Only surpport one layer nested list.')
|
||||
return [
|
||||
self.save_image(file_prefix + f'_{rank}_{idx}', v,
|
||||
image_postfix) for idx, v in enumerate(images)
|
||||
]
|
||||
np_shape = images.shape
|
||||
# 4D
|
||||
shape_str = '_'.join([str(v) for v in np_shape])
|
||||
@@ -378,9 +410,12 @@ class ProbeData():
|
||||
images = images.reshape(images.shape[:-1])
|
||||
file_list = []
|
||||
for idx in range(np_shape[0]):
|
||||
file_path = os.path.join(file_prefix, f'probe_{rank}_{idx}_[{shape_str}].{image_postfix}')
|
||||
file_path = os.path.join(
|
||||
file_prefix,
|
||||
f'probe_{rank}_{idx}_[{shape_str}].{image_postfix}')
|
||||
byio = BytesIO()
|
||||
Image.fromarray(images[idx, ...]).save(byio, self.get_format(self.image_postfix))
|
||||
Image.fromarray(images[idx, ...]).save(
|
||||
byio, self.get_format(self.image_postfix))
|
||||
self.media_handler.append(byio, file_path)
|
||||
file_list.append(file_path)
|
||||
return file_list
|
||||
@@ -392,7 +427,8 @@ class ProbeData():
|
||||
images = images.reshape(images.shape[:-1])
|
||||
file_path = file_prefix + f'_probe_{rank}_[{shape_str}].{image_postfix}'
|
||||
byio = BytesIO()
|
||||
Image.fromarray(images).save(byio, self.get_format(self.image_postfix))
|
||||
Image.fromarray(images).save(
|
||||
byio, self.get_format(self.image_postfix))
|
||||
self.media_handler.append(byio, file_path)
|
||||
return file_path
|
||||
else:
|
||||
@@ -401,13 +437,14 @@ class ProbeData():
|
||||
elif len(np_shape) == 2:
|
||||
file_path = file_prefix + f'_probe_{rank}_[{shape_str}].{image_postfix}'
|
||||
byio = BytesIO()
|
||||
Image.fromarray(images).save(byio, self.get_format(self.image_postfix))
|
||||
Image.fromarray(images).save(byio,
|
||||
self.get_format(self.image_postfix))
|
||||
self.media_handler.append(byio, file_path)
|
||||
return file_path
|
||||
else:
|
||||
raise f"Ensure your data's dim is BWHC or WHC or WH, and channel is 1 or 3 for {file_prefix}"
|
||||
|
||||
def save_npy(self, file_prefix, data, rank = 0):
|
||||
def save_npy(self, file_prefix, data, rank=0):
|
||||
shape_str = '_'.join([str(v) for v in data.shape])
|
||||
file_path = file_prefix + f'_{rank}_{shape_str}.npy'
|
||||
byio = BytesIO()
|
||||
@@ -420,8 +457,9 @@ class ProbeData():
|
||||
with FS.put_to(html_prefix) as local_path:
|
||||
with open(local_path, 'w') as f:
|
||||
f.writelines('<meta charset="utf-8">\n')
|
||||
f.writelines('<style>input{height:' + f'{height}px;' +
|
||||
'opacity:1.0;} textarea {font-size: 32px;}</style>\n')
|
||||
f.writelines(
|
||||
'<style>input{height:' + f'{height}px;' +
|
||||
'opacity:1.0;} textarea {font-size: 32px;}</style>\n')
|
||||
f.writelines('<br><hr/>\n')
|
||||
all_ranks = list()
|
||||
is_textarea = False
|
||||
@@ -433,16 +471,16 @@ class ProbeData():
|
||||
one_label = one_label.replace('<', '<').replace(
|
||||
'>', '>')
|
||||
try:
|
||||
url = FS.get_url(one_path,
|
||||
lifecycle=3600 * 365 * 24).replace(
|
||||
'.oss-internal.aliyun-inc.',
|
||||
'.oss.aliyuncs.').replace(
|
||||
'-internal', '')
|
||||
except:
|
||||
url = FS.get_url(
|
||||
one_path, lifecycle=3600 * 365 * 24).replace(
|
||||
'.oss-internal.aliyun-inc.',
|
||||
'.oss.aliyuncs.').replace('-internal', '')
|
||||
except Exception:
|
||||
url = one_path
|
||||
if len(one_label) > 10 and idx == len(save_path) - 1:
|
||||
is_textarea = True
|
||||
if self.is_video and one_path.endswith(self.video_postfix):
|
||||
if self.is_video and one_path.endswith(
|
||||
self.video_postfix):
|
||||
one_rank += f'<td align="center"><video height="{height}" controls="">'
|
||||
one_rank += f'<source src="{url}" type="video/mp4"></video>'
|
||||
if idx == len(save_path) - 1 and is_textarea:
|
||||
@@ -467,16 +505,27 @@ class ProbeData():
|
||||
def distribute(self):
|
||||
return self._distribute_dict
|
||||
|
||||
def save_one_media(self, idx, v, prefix_path, image_postfix, video_postfix, rank = 0):
|
||||
def save_one_media(self,
|
||||
idx,
|
||||
v,
|
||||
prefix_path,
|
||||
image_postfix,
|
||||
video_postfix,
|
||||
rank=0):
|
||||
ret_label = None
|
||||
if self.is_image:
|
||||
ret_medias = self.save_image(prefix_path, v,
|
||||
image_postfix, rank = rank)
|
||||
ret_medias = self.save_image(prefix_path,
|
||||
v,
|
||||
image_postfix,
|
||||
rank=rank)
|
||||
elif self.is_video:
|
||||
ret_medias = self.save_video(prefix_path, v,
|
||||
video_postfix, fps=self.fps, rank = rank)
|
||||
ret_medias = self.save_video(prefix_path,
|
||||
v,
|
||||
video_postfix,
|
||||
fps=self.fps,
|
||||
rank=rank)
|
||||
else:
|
||||
ret_data = self.save_npy(prefix_path, v, rank = rank)
|
||||
ret_data = self.save_npy(prefix_path, v, rank=rank)
|
||||
return ret_data, ret_label
|
||||
ret_data = ret_medias if isinstance(ret_medias, list) else [ret_medias]
|
||||
if self.build_html:
|
||||
@@ -484,14 +533,10 @@ class ProbeData():
|
||||
if isinstance(self.build_label, str):
|
||||
ret_label = [self.build_label for _ in ret_medias]
|
||||
elif isinstance(self.build_label[idx], list):
|
||||
assert len(self.build_label[idx]) == len(
|
||||
ret_medias)
|
||||
assert len(self.build_label[idx]) == len(ret_medias)
|
||||
ret_label = self.build_label[idx]
|
||||
else:
|
||||
ret_label = [
|
||||
self.build_label[idx]
|
||||
for _ in ret_medias
|
||||
]
|
||||
ret_label = [self.build_label[idx] for _ in ret_medias]
|
||||
else:
|
||||
if isinstance(self.build_label, str):
|
||||
ret_label = [self.build_label]
|
||||
@@ -499,7 +544,11 @@ class ProbeData():
|
||||
ret_label = [self.build_label[idx]]
|
||||
return ret_data, ret_label
|
||||
|
||||
def presave(self, prefix=None, image_postfix='jpg', video_postfix='mp4', rank = 0):
|
||||
def presave(self,
|
||||
prefix=None,
|
||||
image_postfix='jpg',
|
||||
video_postfix='mp4',
|
||||
rank=0):
|
||||
self.image_postfix = image_postfix
|
||||
self.video_postfix = video_postfix
|
||||
if isinstance(self.data, np.ndarray):
|
||||
@@ -507,11 +556,18 @@ class ProbeData():
|
||||
raise 'You should provide the save prefix for array sample.'
|
||||
# save jpg
|
||||
if self.is_image:
|
||||
ret_data = self.save_image(prefix, self.data, image_postfix, rank = rank)
|
||||
ret_data = self.save_image(prefix,
|
||||
self.data,
|
||||
image_postfix,
|
||||
rank=rank)
|
||||
elif self.is_video:
|
||||
ret_data = self.save_video(prefix, self.data, video_postfix, fps=self.fps, rank = rank)
|
||||
ret_data = self.save_video(prefix,
|
||||
self.data,
|
||||
video_postfix,
|
||||
fps=self.fps,
|
||||
rank=rank)
|
||||
else:
|
||||
ret_data = self.save_npy(prefix, self.data, rank = rank)
|
||||
ret_data = self.save_npy(prefix, self.data, rank=rank)
|
||||
self.media_handler.sync()
|
||||
self.media_handler.clear()
|
||||
if isinstance(ret_data, list):
|
||||
@@ -525,7 +581,7 @@ class ProbeData():
|
||||
ret_label.append(self.build_label)
|
||||
if not len(ret_data[0]) == len(ret_label[0]):
|
||||
raise f"The {prefix} label's length should be equal with 1st dim {self.data.shape[0]}."
|
||||
self.data = {"ret_data": ret_data, "ret_label": ret_label}
|
||||
self.data = {'ret_data': ret_data, 'ret_label': ret_label}
|
||||
else:
|
||||
self.data = ret_data
|
||||
self.is_presave = True
|
||||
@@ -535,16 +591,20 @@ class ProbeData():
|
||||
ret_label = []
|
||||
for idx, v in enumerate(self.data):
|
||||
prefix_path = os.path.join(prefix, f'{idx}')
|
||||
ret_one_data, ret_one_label = self.save_one_media(idx, v,
|
||||
prefix_path,
|
||||
image_postfix,
|
||||
video_postfix,
|
||||
rank=rank)
|
||||
ret_one_data, ret_one_label = self.save_one_media(
|
||||
idx,
|
||||
v,
|
||||
prefix_path,
|
||||
image_postfix,
|
||||
video_postfix,
|
||||
rank=rank)
|
||||
ret_data.append(ret_one_data)
|
||||
ret_label.append(ret_one_label) if ret_one_label is not None else ret_label
|
||||
ret_label.append(
|
||||
ret_one_label
|
||||
) if ret_one_label is not None else ret_label
|
||||
self.media_handler.sync()
|
||||
self.media_handler.clear()
|
||||
self.data = {"ret_data": ret_data, "ret_label": ret_label}
|
||||
self.data = {'ret_data': ret_data, 'ret_label': ret_label}
|
||||
self.is_presave = True
|
||||
elif isinstance(self.data, dict):
|
||||
if not self.basic_type:
|
||||
@@ -552,31 +612,38 @@ class ProbeData():
|
||||
ret_label = []
|
||||
for k, v in self.data.items():
|
||||
prefix_path = os.path.join(prefix, f'{k}_')
|
||||
ret_one_data, ret_one_label = self.save_one_media(k, v,
|
||||
prefix_path,
|
||||
image_postfix,
|
||||
video_postfix,
|
||||
rank = rank)
|
||||
ret_one_data, ret_one_label = self.save_one_media(
|
||||
k,
|
||||
v,
|
||||
prefix_path,
|
||||
image_postfix,
|
||||
video_postfix,
|
||||
rank=rank)
|
||||
ret_data.append(ret_one_data)
|
||||
ret_label.append(ret_one_label) if ret_one_label is not None else ret_label
|
||||
ret_label.append(
|
||||
ret_one_label
|
||||
) if ret_one_label is not None else ret_label
|
||||
self.media_handler.sync()
|
||||
self.media_handler.clear()
|
||||
self.data = {"ret_data": ret_data, "ret_label": ret_label}
|
||||
self.data = {'ret_data': ret_data, 'ret_label': ret_label}
|
||||
self.is_presave = True
|
||||
|
||||
def to_log(self, prefix=None, image_postfix='jpg', video_postfix='mp4', rank = 0):
|
||||
def to_log(self,
|
||||
prefix=None,
|
||||
image_postfix='jpg',
|
||||
video_postfix='mp4',
|
||||
rank=0):
|
||||
if not self.is_presave:
|
||||
self.presave(prefix, image_postfix, video_postfix, rank = rank)
|
||||
self.presave(prefix, image_postfix, video_postfix, rank=rank)
|
||||
if not self.is_presave:
|
||||
return self.data
|
||||
if isinstance(self.data, str):
|
||||
return self.data
|
||||
elif isinstance(self.data, dict):
|
||||
ret_data, ret_label = self.data["ret_data"], self.data["ret_label"]
|
||||
ret_data, ret_label = self.data['ret_data'], self.data['ret_label']
|
||||
if self.build_html:
|
||||
html_prefix = prefix + '_probe.html'
|
||||
html_file = self.save_html(html_prefix, ret_data,
|
||||
ret_label)
|
||||
html_file = self.save_html(html_prefix, ret_data, ret_label)
|
||||
return {'ori_file': ret_data, 'html': html_file}
|
||||
else:
|
||||
return {'ori_file': ret_data}
|
||||
@@ -584,15 +651,15 @@ class ProbeData():
|
||||
ret_data, ret_label = [], []
|
||||
for one_data in self.data:
|
||||
if isinstance(one_data, dict):
|
||||
one_ret_data, one_ret_label = one_data["ret_data"], one_data["ret_label"]
|
||||
one_ret_data, one_ret_label = one_data[
|
||||
'ret_data'], one_data['ret_label']
|
||||
ret_data.extend(one_ret_data)
|
||||
ret_label.extend(one_ret_label)
|
||||
elif isinstance(one_data, str):
|
||||
ret_data.append(one_data)
|
||||
if (self.is_image or self.is_video) and self.build_html:
|
||||
html_prefix = prefix + '_probe.html'
|
||||
html_file = self.save_html(html_prefix, ret_data,
|
||||
ret_label)
|
||||
html_file = self.save_html(html_prefix, ret_data, ret_label)
|
||||
return {'ori_file': ret_data, 'html': html_file}
|
||||
else:
|
||||
return {'ori_file': ret_data}
|
||||
|
||||
@@ -1,4 +1,5 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from enum import Enum
|
||||
|
||||
|
||||
@@ -7,17 +8,19 @@ class Media(Enum):
|
||||
IMAGE = 2
|
||||
VIDEO = 3
|
||||
AUDIO = 4
|
||||
IMAGE_PAIR = 5
|
||||
|
||||
|
||||
class HtmlVisualization(object):
|
||||
def __init__(
|
||||
self,
|
||||
allow_annotation=False,
|
||||
slice_size=1000,
|
||||
align='center',
|
||||
width_scale='60%',
|
||||
title='Visualization',
|
||||
):
|
||||
def __init__(self,
|
||||
allow_annotation=False,
|
||||
slice_size=1000,
|
||||
align='center',
|
||||
width_scale='60%',
|
||||
title='Visualization',
|
||||
height=600,
|
||||
width=None,
|
||||
text_cols=40):
|
||||
self.content_list = []
|
||||
self.rows_meta = []
|
||||
self.allow_annotation = allow_annotation
|
||||
@@ -27,48 +30,136 @@ class HtmlVisualization(object):
|
||||
self.title = title
|
||||
self.html_start = '<html>'
|
||||
self.html_head = f'<head><meta charset="utf-8"><title>{title}</title></head>'
|
||||
self.html_style = '''
|
||||
<style>
|
||||
table {
|
||||
border-collapse: collapse;
|
||||
}
|
||||
td {
|
||||
width: "{width_scale}";
|
||||
align: "{align}";
|
||||
margin: 0px;
|
||||
border: 0px;
|
||||
padding: 0px;
|
||||
vertical-align: top;
|
||||
}
|
||||
video {
|
||||
margin: 0px;
|
||||
border: 0px solid #ccc;
|
||||
padding: 0px;
|
||||
}
|
||||
textarea {
|
||||
margin: 0px;
|
||||
border: 0px;
|
||||
padding: 0px;
|
||||
resize: none;
|
||||
border: 1px solid #ccc;
|
||||
}
|
||||
</style>
|
||||
<script>
|
||||
function adjustHeight() {
|
||||
const textareas = document.querySelectorAll('textarea');
|
||||
textareas.forEach(textarea => {
|
||||
const td = textarea.parentNode;
|
||||
const tdHeight = td.clientHeight;
|
||||
textarea.style.height = tdHeight + 'px';
|
||||
});
|
||||
}
|
||||
window.onload = adjustHeight;
|
||||
window.onresize = adjustHeight;
|
||||
</script>
|
||||
'''.replace('{width_scale}',
|
||||
self.width_scale).replace('{align}', self.align)
|
||||
self.html_body = '<body>{BODY}</body>\n'
|
||||
self.height = height if height is not None else '600'
|
||||
self.width = width if width is not None else 'auto'
|
||||
self.text_cols = text_cols if text_cols is not None else 'auto'
|
||||
self.html_style = ('''
|
||||
<style> \n
|
||||
.container {
|
||||
display: flex;
|
||||
position: relative; \n
|
||||
overflow: hidden; \n
|
||||
justify-content: center; \n
|
||||
align-items: center; \n
|
||||
width: 600; \n
|
||||
height: {pair_height};
|
||||
border: 2px solid #ccc; \n
|
||||
} \n
|
||||
.image {
|
||||
display: flex;
|
||||
position: absolute; \n
|
||||
width: 100%; \n
|
||||
height: 100%; \n
|
||||
transition: 0.4s ease; \n
|
||||
}\n
|
||||
.image img {
|
||||
width: 100%; \n
|
||||
height: 100%; \n
|
||||
object-fit: contain; \n
|
||||
} \n
|
||||
.slider {
|
||||
position: absolute; \n
|
||||
cursor: ew-resize; \n
|
||||
height: 100%; \n
|
||||
background-color: rgba(255, 255, 255, 0.5); \n
|
||||
z-index: 10; \n
|
||||
} \n
|
||||
video { \n
|
||||
width: auto;
|
||||
height: 100%;
|
||||
margin: 0px; \n
|
||||
border: 0px solid #ccc; \n
|
||||
padding: 0px; \n
|
||||
} \n
|
||||
textarea { \n
|
||||
margin: 0px; \n
|
||||
border: 0px; \n
|
||||
padding: 0px; \n
|
||||
resize: none; \n
|
||||
border: 1px solid #ccc; \n
|
||||
} \n
|
||||
</style> \n
|
||||
\n
|
||||
'''.replace('{width_scale}', self.width_scale).replace(
|
||||
'{align}', self.align).replace('{pair_height}', f'{self.height}'))
|
||||
|
||||
self.html_body_script = '''
|
||||
<script>\n
|
||||
const containers = document.querySelectorAll('.container'); \n
|
||||
containers.forEach(container => {\n
|
||||
let isDragging = true;\n
|
||||
const slider = container.querySelector('.slider')\n
|
||||
const image2 = container.querySelector('#image2')\n
|
||||
|
||||
container.addEventListener('mousedown', () => {\n
|
||||
isDragging = true;\n
|
||||
});\n
|
||||
|
||||
|
||||
container.addEventListener('mouseup', () => {\n
|
||||
isDragging = true;\n
|
||||
});\n
|
||||
|
||||
container.addEventListener('mousemove', (event) => {\n
|
||||
if (!isDragging) return;\n
|
||||
const { clientX } = event;\n
|
||||
|
||||
const { left, width } = container.getBoundingClientRect();\n
|
||||
|
||||
let percentage = (clientX - left) / width * 100;\n
|
||||
|
||||
|
||||
// 限制百分比在0到100之间\n
|
||||
|
||||
percentage = Math.max(0, Math.min(100, percentage));\n
|
||||
|
||||
image2.style.clipPath = `inset(0 ${100 - percentage}% 0 0)`;\n
|
||||
|
||||
slider.style.left = `${percentage}%`;\n
|
||||
|
||||
console.info(slider.style.left);\n
|
||||
|
||||
});\n
|
||||
// 初始化滑块位置\n
|
||||
slider.style.left = '50%';\n
|
||||
});\n
|
||||
</script>\n
|
||||
<script> \n
|
||||
const videos = document.querySelectorAll('video'); \n
|
||||
\n
|
||||
const observer = new IntersectionObserver((entries) => { \n
|
||||
entries.forEach(entry => { \n
|
||||
if (entry.isIntersecting) { \n
|
||||
const video = entry.target; \n
|
||||
video.src = video.dataset.src; \n
|
||||
video.load(); \n
|
||||
observer.unobserve(video); \n
|
||||
} \n
|
||||
}); \n
|
||||
}); \n
|
||||
\n
|
||||
videos.forEach(video => { \n
|
||||
observer.observe(video); \n
|
||||
}); \n
|
||||
\n
|
||||
function adjustHeight() { \n
|
||||
const textareas = document.querySelectorAll('textarea'); \n
|
||||
textareas.forEach(textarea => { \n
|
||||
const td = textarea.parentNode; \n
|
||||
const tdHeight = td.clientHeight; \n
|
||||
textarea.style.height = tdHeight + 'px'; \n
|
||||
}); \n
|
||||
} \n
|
||||
window.onload = adjustHeight; \n
|
||||
window.onresize = adjustHeight; \n
|
||||
</script> \n
|
||||
|
||||
'''
|
||||
|
||||
self.html_body = '<body>{BODY}\n' + self.html_body_script + '</body>\n'
|
||||
|
||||
self.html_end = '</html>'
|
||||
|
||||
self.html_script = '''
|
||||
<script>
|
||||
function saveSamples() {
|
||||
@@ -89,6 +180,7 @@ class HtmlVisualization(object):
|
||||
a.click();
|
||||
}
|
||||
</script>
|
||||
|
||||
'''
|
||||
self.label_button = (
|
||||
'<table><tr><td>' +
|
||||
@@ -99,55 +191,73 @@ class HtmlVisualization(object):
|
||||
content='',
|
||||
label='',
|
||||
type=Media.TEXT,
|
||||
content_height=400,
|
||||
content_width=600):
|
||||
show_label=True,
|
||||
cols_span=1):
|
||||
if type == Media.TEXT:
|
||||
ret_str = '<td><textarea' # noqa: E501
|
||||
# if content_height is not None:
|
||||
# rows = f"rows={content_height//30}"
|
||||
# ret_str += f" {rows}"
|
||||
if content_width is not None:
|
||||
cols = f"cols={content_width//15}"
|
||||
ret_str = '<textarea' # noqa: E501
|
||||
if self.height is not None:
|
||||
rows = f"rows={self.height//30}"
|
||||
ret_str += f" {rows}"
|
||||
if self.width is not None:
|
||||
cols = f"cols={self.text_cols * cols_span}"
|
||||
ret_str += f" {cols}"
|
||||
ret_str += f'>"{content}"</textarea></td>\n'
|
||||
sec_ret_str = f'<td align="center"><font size="3"><strong>{label}<strong></font></td>\n'
|
||||
return [ret_str, sec_ret_str]
|
||||
ret_str += f'>"{content}"</textarea>'
|
||||
sec_ret_str = f'<font size="3"><strong>{label}<strong></font>' if show_label else ''
|
||||
elif type == Media.IMAGE:
|
||||
ret_str = f'<td><img src="{content}"'
|
||||
if content_height is not None:
|
||||
height = f'height="{content_height}"'
|
||||
ret_str = f'<img src="{content}"'
|
||||
if self.height is not None:
|
||||
height = f'height="{self.height}"'
|
||||
ret_str += f" {height}"
|
||||
if content_width is not None:
|
||||
width = f'width="{content_width}"'
|
||||
if self.width is not None:
|
||||
width = f'width="{self.width}"'
|
||||
ret_str += f" {width}"
|
||||
ret_str += ' ></td>\n'
|
||||
sec_ret_str = f'<td align="center"><font size="3"><strong>{label}<strong></font></td>\n'
|
||||
return [ret_str, sec_ret_str]
|
||||
ret_str += ' >'
|
||||
sec_ret_str = f'<font size="3"><strong>{label}<strong></font>' if show_label else ''
|
||||
elif type == Media.VIDEO:
|
||||
ret_str = '<td><video' # noqa
|
||||
if content_height is not None:
|
||||
height = f'height="{content_height}"'
|
||||
ret_str = '<video' # noqa
|
||||
if self.height is not None:
|
||||
height = f'height="{self.width}"'
|
||||
ret_str += f" {height}"
|
||||
if content_width is not None:
|
||||
width = f'width="{content_width}"'
|
||||
if self.width is not None:
|
||||
width = f'width="{self.width}"'
|
||||
ret_str += f" {width}"
|
||||
ret_str += ' controls>'
|
||||
ret_str += f'<source src="{content}" type="video/mp4"></video></td>\n'
|
||||
sec_ret_str = f'<td align="center"><font size="3"><strong>{label}<strong></font></td>\n'
|
||||
return [ret_str, sec_ret_str]
|
||||
ret_str += ' preload="none" controls>'
|
||||
ret_str += f'<source src="{content}" type="video/mp4"></video>'
|
||||
sec_ret_str = f'<font size="3"><strong>{label}<strong></font>' if show_label else ''
|
||||
elif type == Media.AUDIO:
|
||||
ret_str = f'<td><audio src="{content}" controls></td>\n'
|
||||
sec_ret_str = f'<td align="center"><font size="3"><strong>{label}<strong></font></td>\n'
|
||||
return [ret_str, sec_ret_str]
|
||||
ret_str = f'<audio src="{content}" controls>'
|
||||
sec_ret_str = f'<font size="3"><strong>{label}<strong></font>' if show_label else ''
|
||||
elif type == Media.IMAGE_PAIR:
|
||||
assert isinstance(content, (list, tuple)) and len(content) == 2
|
||||
ret_str = '\n'
|
||||
ret_str += ' <div class="container"'
|
||||
ret_str += (
|
||||
f'> \n'
|
||||
f' <div class="image" id="image1">' # noqa
|
||||
f' <img src="{content[1]}" alt="before">\n' # noqa
|
||||
f' </div>\n' # noqa
|
||||
f' <div class="image" id="image2" style="clip-path: inset(0 50% 0 0);">\n' # noqa
|
||||
f' <img src="{content[0]}" alt="after">\n' # noqa
|
||||
f' </div>\n' # noqa
|
||||
f' <div class="slider" id="slider"></div>\n' # noqa
|
||||
f'')
|
||||
sec_ret_str = f'<font size="3"><strong>{label}<strong></font>' if show_label else ''
|
||||
else:
|
||||
raise NotImplementedError
|
||||
if cols_span > 1:
|
||||
ret_str = f'<th colspan="{cols_span}">{ret_str}</th>\n'
|
||||
sec_ret_str = f'<th colspan="{cols_span}">{sec_ret_str}</th>\n' if not sec_ret_str == '' else sec_ret_str
|
||||
else:
|
||||
ret_str = f'<td>{ret_str}</td>\n'
|
||||
sec_ret_str = f'<td align="center">{sec_ret_str}</td>\n' if not sec_ret_str == '' else sec_ret_str
|
||||
return [ret_str, sec_ret_str]
|
||||
|
||||
def format_row(self):
|
||||
sample_id = 0
|
||||
all_sample_html = []
|
||||
for one_content, one_row_meta in zip(self.content_list,
|
||||
self.rows_meta):
|
||||
one_row_str = '<table><tr>'
|
||||
one_row_str = '<tr>'
|
||||
one_row_str += '\n'.join([v[0] for v in one_content])
|
||||
if self.allow_annotation:
|
||||
row_meta = '#;#'.join(one_row_meta)
|
||||
@@ -159,23 +269,23 @@ class HtmlVisualization(object):
|
||||
one_row_str += '\n'.join([v[1] for v in one_content]) # noqa
|
||||
if self.allow_annotation: # noqa
|
||||
one_row_str += f'<td></td>\n' # noqa
|
||||
one_row_str += '</tr></table>'
|
||||
one_row_str += '</tr>'
|
||||
if self.allow_annotation:
|
||||
one_row_str = f'<label for="sample{sample_id}">{one_row_str}</label>'
|
||||
all_sample_html.append(one_row_str)
|
||||
sample_id += 1
|
||||
|
||||
return '\n'.join(all_sample_html)
|
||||
return '<table>' + '\n'.join(all_sample_html) + '</table>'
|
||||
|
||||
def add_record(self,
|
||||
content='',
|
||||
content,
|
||||
label='',
|
||||
type=Media.TEXT,
|
||||
row_id=1,
|
||||
col_id=1,
|
||||
cols_span=1,
|
||||
annotation_meta=None,
|
||||
content_height=None,
|
||||
content_width=None):
|
||||
show_label=True):
|
||||
if row_id >= len(self.content_list):
|
||||
self.content_list.append([])
|
||||
self.rows_meta.append([])
|
||||
@@ -185,8 +295,11 @@ class HtmlVisualization(object):
|
||||
if col_id > len(self.content_list[row_id]):
|
||||
raise RuntimeError(
|
||||
'col_id should be next number of the last col_id.')
|
||||
format_col = self.format_col(content, f"{row_id}-{col_id}: {label}",
|
||||
type, content_height, content_width)
|
||||
format_col = self.format_col(content,
|
||||
f"{row_id}-{col_id}: {label}",
|
||||
type,
|
||||
show_label=show_label,
|
||||
cols_span=cols_span)
|
||||
|
||||
annotation_meta = annotation_meta if annotation_meta else ''
|
||||
if col_id == len(self.content_list[row_id]):
|
||||
@@ -209,49 +322,3 @@ class HtmlVisualization(object):
|
||||
ret_html = '\n'.join(ret_html_list)
|
||||
with open(path, 'w') as f:
|
||||
f.write(ret_html)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
from scepter.modules.utils.config import Config
|
||||
from scepter.modules.utils.file_system import FS
|
||||
FS.init_fs_client(Config(cfg_dict={}, load=False))
|
||||
|
||||
image_content_oss = '0_probe_0_[1024_2048_3].jpg'
|
||||
content_oss = '6UTWGRG1lx08iRBx5REA01041200dzcb0E010.mp4'
|
||||
caption = 'a little girl says hello.'
|
||||
|
||||
html_ins = HtmlVisualization(allow_annotation=True,
|
||||
slice_size=1000,
|
||||
title='Visualization',
|
||||
width_scale='100%')
|
||||
|
||||
for i in range(4):
|
||||
content_url = FS.get_url(content_oss, skip_check=True)
|
||||
html_ins.add_record(content=content_url,
|
||||
label='caption',
|
||||
type=Media.VIDEO,
|
||||
row_id=i,
|
||||
col_id=0,
|
||||
annotation_meta=None,
|
||||
content_height=600,
|
||||
content_width=None)
|
||||
html_ins.add_record(content=caption,
|
||||
label='caption',
|
||||
type=Media.TEXT,
|
||||
row_id=i,
|
||||
col_id=1,
|
||||
annotation_meta=None,
|
||||
content_height=600,
|
||||
content_width=750)
|
||||
image_content_url = FS.get_url(image_content_oss, skip_check=True)
|
||||
html_ins.add_record(content=image_content_url,
|
||||
label='caption',
|
||||
type=Media.IMAGE,
|
||||
row_id=i,
|
||||
col_id=2,
|
||||
annotation_meta=None,
|
||||
content_height=600,
|
||||
content_width=None)
|
||||
|
||||
with FS.put_to('visualize.html') as local_path:
|
||||
html_ins.save_html(local_path)
|
||||
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,367 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import os
|
||||
|
||||
from scepter.modules.utils.file_system import FS
|
||||
|
||||
|
||||
def download_image(image, local_path=None):
|
||||
if not FS.exists(local_path):
|
||||
local_path = FS.get_from(image, local_path=local_path)
|
||||
return local_path
|
||||
|
||||
|
||||
def get_examples(cache_dir):
|
||||
print('Downloading Examples ...')
|
||||
examples = [
|
||||
[
|
||||
'Facial Editing',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/e33edc106953.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/e33edc106953.png')), None,
|
||||
None, '{image} let the man smile', 6666
|
||||
],
|
||||
[
|
||||
'Facial Editing',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/5d2bcc91a3e9.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/5d2bcc91a3e9.png')), None,
|
||||
None, 'let the man in {image} wear sunglasses', 9999
|
||||
],
|
||||
[
|
||||
'Facial Editing',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/3a52eac708bd.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/3a52eac708bd.png')), None,
|
||||
None, '{image} red hair', 9999
|
||||
],
|
||||
[
|
||||
'Facial Editing',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/3f4dc464a0ea.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/3f4dc464a0ea.png')), None,
|
||||
None, '{image} let the man serious', 99999
|
||||
],
|
||||
[
|
||||
'Controllable Generation',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/131ca90fd2a9.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/131ca90fd2a9.png')), None, None,
|
||||
'"A person sits contemplatively on the ground, surrounded by falling autumn leaves. Dressed in a green sweater and dark blue pants, they rest their chin on their hand, exuding a relaxed demeanor. Their stylish checkered slip-on shoes add a touch of flair, while a black purse lies in their lap. The backdrop of muted brown enhances the warm, cozy atmosphere of the scene." , generate the image that corresponds to the given scribble {image}.',
|
||||
613725
|
||||
],
|
||||
[
|
||||
'Render Text',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/33e9f27c2c48.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/33e9f27c2c48.png')),
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/33e9f27c2c48_mask.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/33e9f27c2c48_mask.png')), None,
|
||||
'Put the text "C A T" at the position marked by mask in the {image}',
|
||||
6666
|
||||
],
|
||||
[
|
||||
'Style Transfer',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/9e73e7eeef55.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/9e73e7eeef55.png')), None,
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/2e02975293d6.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/2e02975293d6.png')),
|
||||
'edit {image} based on the style of {image1} ', 99999
|
||||
],
|
||||
[
|
||||
'Outpainting',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/f2b22c08be3f.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/f2b22c08be3f.png')),
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/f2b22c08be3f_mask.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/f2b22c08be3f_mask.png')), None,
|
||||
'Could the {image} be widened within the space designated by mask, while retaining the original?',
|
||||
6666
|
||||
],
|
||||
[
|
||||
'Image Segmentation',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/db3ebaa81899.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/db3ebaa81899.png')), None,
|
||||
None, '{image} Segmentation', 6666
|
||||
],
|
||||
[
|
||||
'Depth Estimation',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/f1927c4692ba.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/f1927c4692ba.png')), None,
|
||||
None, '{image} Depth Estimation', 6666
|
||||
],
|
||||
[
|
||||
'Pose Estimation',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/014e5bf3b4d1.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/014e5bf3b4d1.png')), None,
|
||||
None, '{image} distinguish the poses of the figures', 999999
|
||||
],
|
||||
[
|
||||
'Scribble Extraction',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/5f59a202f8ac.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/5f59a202f8ac.png')), None,
|
||||
None, 'Generate a scribble of {image}, please.', 6666
|
||||
],
|
||||
[
|
||||
'Mosaic',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/3a2f52361eea.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/3a2f52361eea.png')), None,
|
||||
None, 'Adapt {image} into a mosaic representation.', 6666
|
||||
],
|
||||
[
|
||||
'Edge map Extraction',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/b9d1e519d6e5.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/b9d1e519d6e5.png')), None,
|
||||
None, 'Get the edge-enhanced result for {image}.', 6666
|
||||
],
|
||||
[
|
||||
'Grayscale',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/c4ebbe2ba29b.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/c4ebbe2ba29b.png')), None,
|
||||
None, 'transform {image} into a black and white one', 6666
|
||||
],
|
||||
[
|
||||
'Contour Extraction',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/19652d0f6c4b.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/19652d0f6c4b.png')), None, None,
|
||||
'Would you be able to make a contour picture from {image} for me?',
|
||||
6666
|
||||
],
|
||||
[
|
||||
'Controllable Generation',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/249cda2844b7.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/249cda2844b7.png')), None, None,
|
||||
'Following the segmentation outcome in mask of {image}, develop a real-life image using the explanatory note in "a mighty cat lying on the bed”.',
|
||||
6666
|
||||
],
|
||||
[
|
||||
'Controllable Generation',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/411f6c4b8e6c.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/411f6c4b8e6c.png')), None, None,
|
||||
'use the depth map {image} and the text caption "a cut white cat" to create a corresponding graphic image',
|
||||
999999
|
||||
],
|
||||
[
|
||||
'Controllable Generation',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/a35c96ed137a.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/a35c96ed137a.png')), None, None,
|
||||
'help translate this posture schema {image} into a colored image based on the context I provided "A beautiful woman Climbing the climbing wall, wearing a harness and climbing gear, skillfully maneuvering up the wall with her back to the camera, with a safety rope."',
|
||||
3599999
|
||||
],
|
||||
[
|
||||
'Controllable Generation',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/dcb2fc86f1ce.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/dcb2fc86f1ce.png')), None, None,
|
||||
'Transform and generate an image using mosaic {image} and "Monarch butterflies gracefully perch on vibrant purple flowers, showcasing their striking orange and black wings in a lush garden setting." description',
|
||||
6666
|
||||
],
|
||||
[
|
||||
'Controllable Generation',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/4cd4ee494962.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/4cd4ee494962.png')), None, None,
|
||||
'make this {image} colorful as per the "beautiful sunflowers"',
|
||||
6666
|
||||
],
|
||||
[
|
||||
'Controllable Generation',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/a47e3a9cd166.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/a47e3a9cd166.png')), None, None,
|
||||
'Take the edge conscious {image} and the written guideline "A whimsical animated character is depicted holding a delectable cake adorned with blue and white frosting and a drizzle of chocolate. The character wears a yellow headband with a bow, matching a cozy yellow sweater. Her dark hair is styled in a braid, tied with a yellow ribbon. With a golden fork in hand, she stands ready to enjoy a slice, exuding an air of joyful anticipation. The scene is creatively rendered with a charming and playful aesthetic." and produce a realistic image.',
|
||||
613725
|
||||
],
|
||||
[
|
||||
'Controllable Generation',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/d890ed8a3ac2.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/d890ed8a3ac2.png')), None, None,
|
||||
'creating a vivid image based on {image} and description "This image features a delicious rectangular tart with a flaky, golden-brown crust. The tart is topped with evenly sliced tomatoes, layered over a creamy cheese filling. Aromatic herbs are sprinkled on top, adding a touch of green and enhancing the visual appeal. The background includes a soft, textured fabric and scattered white flowers, creating an elegant and inviting presentation. Bright red tomatoes in the upper right corner hint at the fresh ingredients used in the dish."',
|
||||
6666
|
||||
],
|
||||
[
|
||||
'Image Denoising',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/0844a686a179.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/0844a686a179.png')), None, None,
|
||||
'Eliminate noise interference in {image} and maximize the crispness to obtain superior high-definition quality',
|
||||
6666
|
||||
],
|
||||
[
|
||||
'Inpainting',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/fa91b6b7e59b.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/fa91b6b7e59b.png')),
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/fa91b6b7e59b_mask.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/fa91b6b7e59b_mask.png')), None,
|
||||
'Ensure to overhaul the parts of the {image} indicated by the mask.',
|
||||
6666
|
||||
],
|
||||
[
|
||||
'Inpainting',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/632899695b26.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/632899695b26.png')),
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/632899695b26_mask.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/632899695b26_mask.png')), None,
|
||||
'Refashion the mask portion of {image} in accordance with "A yellow egg with a smiling face painted on it"',
|
||||
6666
|
||||
],
|
||||
[
|
||||
'General Editing',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/354d17594afe.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/354d17594afe.png')), None, None,
|
||||
'{image} change the dog\'s posture to walking in the water, and change the background to green plants and a pond.',
|
||||
6666
|
||||
],
|
||||
[
|
||||
'General Editing',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/38946455752b.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/38946455752b.png')), None, None,
|
||||
'{image} change the color of the dress from white to red and the model\'s hair color red brown to blonde.Other parts remain unchanged',
|
||||
6669
|
||||
],
|
||||
[
|
||||
'Facial Editing',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/3ba5202f0cd8.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/3ba5202f0cd8.png')), None, None,
|
||||
'Keep the same facial feature in @3ba5202f0cd8, change the woman\'s clothing from a Blue denim jacket to a white turtleneck sweater and adjust her posture so that she is supporting her chin with both hands. Other aspects, such as background, hairstyle, facial expression, etc, remain unchanged.',
|
||||
99999
|
||||
],
|
||||
[
|
||||
'Facial Editing',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/369365b94725.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/369365b94725.png')), None,
|
||||
None, '{image} Make her looking at the camera', 6666
|
||||
],
|
||||
[
|
||||
'Facial Editing',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/92751f2e4a0e.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/92751f2e4a0e.png')), None,
|
||||
None, '{image} Remove the smile from his face', 9899999
|
||||
],
|
||||
[
|
||||
'Remove Text',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/8530a6711b2e.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/8530a6711b2e.png')), None,
|
||||
None, 'Aim to remove any textual element in {image}', 6666
|
||||
],
|
||||
[
|
||||
'Remove Text',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/c4d7fb28f8f6.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/c4d7fb28f8f6.png')),
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/c4d7fb28f8f6_mask.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/c4d7fb28f8f6_mask.png')), None,
|
||||
'Rub out any text found in the mask sector of the {image}.', 6666
|
||||
],
|
||||
[
|
||||
'Remove Object',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/e2f318fa5e5b.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/e2f318fa5e5b.png')), None, None,
|
||||
'Remove the unicorn in this {image}, ensuring a smooth edit.',
|
||||
99999
|
||||
],
|
||||
[
|
||||
'Remove Object',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/1ae96d8aca00.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/1ae96d8aca00.png')),
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/1ae96d8aca00_mask.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/1ae96d8aca00_mask.png')),
|
||||
None, 'Discard the contents of the mask area from {image}.', 99999
|
||||
],
|
||||
[
|
||||
'Add Object',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/80289f48e511.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/80289f48e511.png')),
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/80289f48e511_mask.png?raw=true',
|
||||
os.path.join(cache_dir,
|
||||
'examples/80289f48e511_mask.png')), None,
|
||||
'add a Hot Air Balloon into the {image}, per the mask', 613725
|
||||
],
|
||||
[
|
||||
'Style Transfer',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/d725cb2009e8.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/d725cb2009e8.png')), None,
|
||||
None, 'Change the style of {image} to colored pencil style', 99999
|
||||
],
|
||||
[
|
||||
'Style Transfer',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/e0f48b3fd010.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/e0f48b3fd010.png')), None,
|
||||
None, 'make {image} to Walt Disney Animation style', 99999
|
||||
],
|
||||
[
|
||||
'Try On',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/ee4ca60b8c96.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/ee4ca60b8c96.png')),
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/ee4ca60b8c96_mask.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/ee4ca60b8c96_mask.png')),
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/ebe825bbfe3c.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/ebe825bbfe3c.png')),
|
||||
'Change the cloth in {image} to the one in {image1}', 99999
|
||||
],
|
||||
[
|
||||
'Workflow',
|
||||
download_image(
|
||||
'https://github.com/ali-vilab/ace-page/blob/main/assets/examples/cb85353c004b.png?raw=true',
|
||||
os.path.join(cache_dir, 'examples/cb85353c004b.png')), None,
|
||||
None, '<workflow> ice cream {image}', 99999
|
||||
],
|
||||
]
|
||||
print('Finish. Start building UI ...')
|
||||
return examples
|
||||
@@ -0,0 +1,95 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
import torch
|
||||
import torchvision.transforms as T
|
||||
from PIL import Image
|
||||
from torchvision.transforms.functional import InterpolationMode
|
||||
|
||||
IMAGENET_MEAN = (0.485, 0.456, 0.406)
|
||||
IMAGENET_STD = (0.229, 0.224, 0.225)
|
||||
|
||||
|
||||
def build_transform(input_size):
|
||||
MEAN, STD = IMAGENET_MEAN, IMAGENET_STD
|
||||
transform = T.Compose([
|
||||
T.Lambda(lambda img: img.convert('RGB') if img.mode != 'RGB' else img),
|
||||
T.Resize((input_size, input_size),
|
||||
interpolation=InterpolationMode.BICUBIC),
|
||||
T.ToTensor(),
|
||||
T.Normalize(mean=MEAN, std=STD)
|
||||
])
|
||||
return transform
|
||||
|
||||
|
||||
def find_closest_aspect_ratio(aspect_ratio, target_ratios, width, height,
|
||||
image_size):
|
||||
best_ratio_diff = float('inf')
|
||||
best_ratio = (1, 1)
|
||||
area = width * height
|
||||
for ratio in target_ratios:
|
||||
target_aspect_ratio = ratio[0] / ratio[1]
|
||||
ratio_diff = abs(aspect_ratio - target_aspect_ratio)
|
||||
if ratio_diff < best_ratio_diff:
|
||||
best_ratio_diff = ratio_diff
|
||||
best_ratio = ratio
|
||||
elif ratio_diff == best_ratio_diff:
|
||||
if area > 0.5 * image_size * image_size * ratio[0] * ratio[1]:
|
||||
best_ratio = ratio
|
||||
return best_ratio
|
||||
|
||||
|
||||
def dynamic_preprocess(image,
|
||||
min_num=1,
|
||||
max_num=12,
|
||||
image_size=448,
|
||||
use_thumbnail=False):
|
||||
orig_width, orig_height = image.size
|
||||
aspect_ratio = orig_width / orig_height
|
||||
|
||||
# calculate the existing image aspect ratio
|
||||
target_ratios = set((i, j) for n in range(min_num, max_num + 1)
|
||||
for i in range(1, n + 1) for j in range(1, n + 1)
|
||||
if i * j <= max_num and i * j >= min_num)
|
||||
target_ratios = sorted(target_ratios, key=lambda x: x[0] * x[1])
|
||||
|
||||
# find the closest aspect ratio to the target
|
||||
target_aspect_ratio = find_closest_aspect_ratio(aspect_ratio,
|
||||
target_ratios, orig_width,
|
||||
orig_height, image_size)
|
||||
|
||||
# calculate the target width and height
|
||||
target_width = image_size * target_aspect_ratio[0]
|
||||
target_height = image_size * target_aspect_ratio[1]
|
||||
blocks = target_aspect_ratio[0] * target_aspect_ratio[1]
|
||||
|
||||
# resize the image
|
||||
resized_img = image.resize((target_width, target_height))
|
||||
processed_images = []
|
||||
for i in range(blocks):
|
||||
box = ((i % (target_width // image_size)) * image_size,
|
||||
(i // (target_width // image_size)) * image_size,
|
||||
((i % (target_width // image_size)) + 1) * image_size,
|
||||
((i // (target_width // image_size)) + 1) * image_size)
|
||||
# split the image
|
||||
split_img = resized_img.crop(box)
|
||||
processed_images.append(split_img)
|
||||
assert len(processed_images) == blocks
|
||||
if use_thumbnail and len(processed_images) != 1:
|
||||
thumbnail_img = image.resize((image_size, image_size))
|
||||
processed_images.append(thumbnail_img)
|
||||
return processed_images
|
||||
|
||||
|
||||
def load_image(image_file, input_size=448, max_num=12):
|
||||
if isinstance(image_file, str):
|
||||
image = Image.open(image_file).convert('RGB')
|
||||
else:
|
||||
image = image_file
|
||||
transform = build_transform(input_size=input_size)
|
||||
images = dynamic_preprocess(image,
|
||||
image_size=input_size,
|
||||
use_thumbnail=True,
|
||||
max_num=max_num)
|
||||
pixel_values = [transform(image) for image in images]
|
||||
pixel_values = torch.stack(pixel_values)
|
||||
return pixel_values
|
||||
@@ -72,6 +72,7 @@ class LargenUI(UIBase):
|
||||
label=self.component_names.scene_image,
|
||||
type='pil',
|
||||
sources=['upload'],
|
||||
transforms=[],
|
||||
layers=False,
|
||||
interactive=True)
|
||||
self.cache_button = gr.Button(
|
||||
@@ -81,6 +82,7 @@ class LargenUI(UIBase):
|
||||
label=self.component_names.subject_image,
|
||||
type='pil',
|
||||
sources=['upload'],
|
||||
transforms=[],
|
||||
layers=False,
|
||||
visible=False,
|
||||
interactive=True)
|
||||
|
||||
@@ -2,7 +2,6 @@
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import os.path
|
||||
import time
|
||||
|
||||
@@ -305,6 +304,7 @@ class DatasetGalleryUI(UIBase):
|
||||
self.preview_src_image = gr.ImageMask(
|
||||
label=self.component_names.preview_src_image,
|
||||
sources=[],
|
||||
transforms=[],
|
||||
layers=False,
|
||||
type='pil',
|
||||
interactive=True)
|
||||
@@ -315,6 +315,7 @@ class DatasetGalleryUI(UIBase):
|
||||
self.preview_src_mask_image = gr.ImageMask(
|
||||
label=self.component_names.preview_src_mask_image,
|
||||
sources=[],
|
||||
transforms=[],
|
||||
layers=False,
|
||||
type='pil',
|
||||
interactive=True)
|
||||
@@ -324,6 +325,7 @@ class DatasetGalleryUI(UIBase):
|
||||
self.preview_taget_image = gr.ImageMask(
|
||||
label=self.component_names.preview_target_image,
|
||||
sources=[],
|
||||
transforms=[],
|
||||
layers=False,
|
||||
type='pil',
|
||||
interactive=True)
|
||||
|
||||
@@ -97,7 +97,7 @@ class TrainerUI(UIBase):
|
||||
reverse=False))
|
||||
|
||||
def create_ui(self):
|
||||
with gr.Tabs():
|
||||
with gr.Group():
|
||||
with gr.Row(variant='panel', equal_height=True):
|
||||
with gr.Column(scale=1, min_width=0, variant='panel'):
|
||||
gr.Markdown(self.component_names.user_direction)
|
||||
@@ -659,15 +659,16 @@ class TrainerUI(UIBase):
|
||||
data_cfg['BATCH_SIZE'] = int(train_batch_size)
|
||||
data_cfg['PROMPT_PREFIX'] = prompt_prefix
|
||||
data_cfg['REPLACE_KEYWORDS'] = replace_keywords
|
||||
for trans in data_cfg['TRANSFORMS']:
|
||||
if trans['NAME'] in [
|
||||
'Resize', 'FlexibleResize', 'CenterCrop',
|
||||
'FlexibleCenterCrop'
|
||||
]:
|
||||
trans['SIZE'] = [
|
||||
int(resolution_height),
|
||||
int(resolution_width)
|
||||
]
|
||||
if 'TRANSFORMS' in data_cfg:
|
||||
for trans in data_cfg['TRANSFORMS']:
|
||||
if trans['NAME'] in [
|
||||
'Resize', 'FlexibleResize', 'CenterCrop',
|
||||
'FlexibleCenterCrop'
|
||||
]:
|
||||
trans['SIZE'] = [
|
||||
int(resolution_height),
|
||||
int(resolution_width)
|
||||
]
|
||||
if data_source in self.component_names.data_source_choices:
|
||||
if ms_data_name.startswith(
|
||||
'http') or ms_data_name.endswith('zip'):
|
||||
@@ -736,7 +737,8 @@ class TrainerUI(UIBase):
|
||||
if os.path.exists(local_data_dir) and os.path.exists(
|
||||
local_file_list):
|
||||
data_cfg.update({
|
||||
'NAME': 'ImageTextPairDataset',
|
||||
'NAME': 'ImageTextPairDataset' if data_cfg['NAME'] == 'ImageTextPairMSDataset' else data_cfg['NAME'],
|
||||
'ENABLE_RESOLUTION_BUCKET': enable_resolution_bucket,
|
||||
'SAMPLER': {
|
||||
'NAME':
|
||||
'ResolutionBatchSampler',
|
||||
@@ -761,11 +763,12 @@ class TrainerUI(UIBase):
|
||||
},
|
||||
'DATA_NUM': data_num
|
||||
})
|
||||
for trans in data_cfg['TRANSFORMS']:
|
||||
if trans['NAME'] == 'Select':
|
||||
trans['META_KEYS'] = [
|
||||
'img_path', 'image_size'
|
||||
]
|
||||
if 'TRANSFORMS' in data_cfg:
|
||||
for trans in data_cfg['TRANSFORMS']:
|
||||
if trans['NAME'] == 'Select':
|
||||
trans['META_KEYS'] = [
|
||||
'img_path', 'image_size'
|
||||
]
|
||||
else:
|
||||
raise Exception(
|
||||
'Cannot find right data format for resolution_bucket'
|
||||
|
||||
@@ -7,6 +7,7 @@ import sys
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.amp as amp
|
||||
import torchvision.transforms as TT
|
||||
from PIL import Image
|
||||
from scepter.modules.solver.registry import SOLVERS
|
||||
|
||||
@@ -8,6 +8,7 @@ import random
|
||||
import sys
|
||||
|
||||
import gradio as gr
|
||||
|
||||
import scepter
|
||||
from scepter.modules.utils.config import Config
|
||||
from scepter.modules.utils.file_system import FS
|
||||
@@ -126,6 +127,12 @@ if __name__ == '__main__':
|
||||
language=args.language,
|
||||
root_work_dir=config.WORK_DIR)
|
||||
print('init inference success!')
|
||||
if ifid == 'ChatBot':
|
||||
from scepter.studio.chatbot.chatbot import ChatBotUI
|
||||
|
||||
interface = ChatBotUI(info['CONFIG'],
|
||||
root_work_dir=config.WORK_DIR)
|
||||
print('init inference success!')
|
||||
if ifid == '':
|
||||
pass # TODO: Add New Features
|
||||
if interface:
|
||||
|
||||
+1
-1
@@ -1,7 +1,7 @@
|
||||
# -*- coding: utf-8 -*-
|
||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||
|
||||
__version__ = '1.1.0'
|
||||
__version__ = '1.2.0'
|
||||
|
||||
version_info = tuple(int(x) for x in __version__.split('.')[0:3])
|
||||
|
||||
|
||||
@@ -0,0 +1,296 @@
|
||||
NAME: ACE_0.6B_512
|
||||
IS_DEFAULT: False
|
||||
DEFAULT_PARAS:
|
||||
PARAS:
|
||||
#
|
||||
INPUT:
|
||||
INPUT_IMAGE:
|
||||
INPUT_MASK:
|
||||
TASK:
|
||||
PROMPT: ""
|
||||
NEGATIVE_PROMPT: ""
|
||||
OUTPUT_HEIGHT: 512
|
||||
OUTPUT_WIDTH: 512
|
||||
SAMPLER: ddim
|
||||
SAMPLE_STEPS: 20
|
||||
GUIDE_SCALE: 4.5
|
||||
GUIDE_RESCALE: 0.5
|
||||
SEED: -1
|
||||
TAR_INDEX: 0
|
||||
OUTPUT:
|
||||
LATENT:
|
||||
IMAGES:
|
||||
SEED:
|
||||
MODULES_PARAS:
|
||||
FIRST_STAGE_MODEL:
|
||||
FUNCTION:
|
||||
- NAME: encode
|
||||
DTYPE: float16
|
||||
INPUT: ["IMAGE"]
|
||||
- NAME: decode
|
||||
DTYPE: float16
|
||||
INPUT: ["LATENT"]
|
||||
#
|
||||
DIFFUSION_MODEL:
|
||||
FUNCTION:
|
||||
- NAME: forward
|
||||
DTYPE: float16
|
||||
INPUT: ["SAMPLE_STEPS", "SAMPLE", "GUIDE_SCALE"]
|
||||
#
|
||||
COND_STAGE_MODEL:
|
||||
FUNCTION:
|
||||
- NAME: encode_list
|
||||
DTYPE: bfloat16
|
||||
INPUT: ["PROMPT"]
|
||||
#
|
||||
TEXT_IDENTIFIER: [ '{image}', '{image1}', '{image2}', '{image3}', '{image4}', '{image5}', '{image6}', '{image7}', '{image8}', '{image9}' ]
|
||||
USE_TEXT_POS_EMBEDDINGS: True
|
||||
#
|
||||
MODEL:
|
||||
NAME: LatentDiffusionACE
|
||||
PRETRAINED_MODEL:
|
||||
IGNORE_KEYS: [ ]
|
||||
SCALE_FACTOR: 0.18215
|
||||
SIZE_FACTOR: 8
|
||||
DECODER_BIAS: 0.5
|
||||
DEFAULT_N_PROMPT: ""
|
||||
TEXT_IDENTIFIER: [ '{image}', '{image1}', '{image2}', '{image3}', '{image4}', '{image5}', '{image6}', '{image7}', '{image8}', '{image9}' ]
|
||||
USE_TEXT_POS_EMBEDDINGS: True
|
||||
#
|
||||
DIFFUSION:
|
||||
NAME: BaseDiffusion
|
||||
PREDICTION_TYPE: eps
|
||||
MIN_SNR_GAMMA:
|
||||
NOISE_SCHEDULER:
|
||||
NAME: LinearScheduler
|
||||
NUM_TIMESTEPS: 1000
|
||||
BETA_MIN: 0.0001
|
||||
BETA_MAX: 0.02
|
||||
#
|
||||
DIFFUSION_MODEL:
|
||||
NAME: ACE
|
||||
PRETRAINED_MODEL: ms://iic/ACE-0.6B-512px@models/dit/ace_0.6b_512px.pth
|
||||
IGNORE_KEYS: [ ]
|
||||
PATCH_SIZE: 2
|
||||
IN_CHANNELS: 4
|
||||
HIDDEN_SIZE: 1152
|
||||
DEPTH: 28
|
||||
NUM_HEADS: 16
|
||||
MLP_RATIO: 4.0
|
||||
PRED_SIGMA: True
|
||||
DROP_PATH: 0.0
|
||||
WINDOW_DIZE: 0
|
||||
Y_CHANNELS: 4096
|
||||
MAX_SEQ_LEN: 1024
|
||||
QK_NORM: True
|
||||
USE_GRAD_CHECKPOINT: True
|
||||
ATTENTION_BACKEND: flash_attn
|
||||
#
|
||||
FIRST_STAGE_MODEL:
|
||||
NAME: AutoencoderKL
|
||||
EMBED_DIM: 4
|
||||
PRETRAINED_MODEL: ms://iic/ACE-0.6B-512px@models/vae/vae.bin
|
||||
IGNORE_KEYS: []
|
||||
#
|
||||
ENCODER:
|
||||
NAME: Encoder
|
||||
CH: 128
|
||||
OUT_CH: 3
|
||||
NUM_RES_BLOCKS: 2
|
||||
IN_CHANNELS: 3
|
||||
ATTN_RESOLUTIONS: [ ]
|
||||
CH_MULT: [ 1, 2, 4, 4 ]
|
||||
Z_CHANNELS: 4
|
||||
DOUBLE_Z: True
|
||||
DROPOUT: 0.0
|
||||
RESAMP_WITH_CONV: True
|
||||
#
|
||||
DECODER:
|
||||
NAME: Decoder
|
||||
CH: 128
|
||||
OUT_CH: 3
|
||||
NUM_RES_BLOCKS: 2
|
||||
IN_CHANNELS: 3
|
||||
ATTN_RESOLUTIONS: [ ]
|
||||
CH_MULT: [ 1, 2, 4, 4 ]
|
||||
Z_CHANNELS: 4
|
||||
DROPOUT: 0.0
|
||||
RESAMP_WITH_CONV: True
|
||||
GIVE_PRE_END: False
|
||||
TANH_OUT: False
|
||||
#
|
||||
COND_STAGE_MODEL:
|
||||
NAME: T5EmbedderHF
|
||||
PRETRAINED_MODEL: ms://iic/ACE-0.6B-512px@models/text_encoder/t5-v1_1-xxl/
|
||||
TOKENIZER_PATH: ms://iic/ACE-0.6B-512px@models/tokenizer/t5-v1_1-xxl
|
||||
LENGTH: 120
|
||||
T5_DTYPE: bfloat16
|
||||
ADDED_IDENTIFIER: [ '{image}', '{caption}', '{mask}', '{ref_image}', '{image1}', '{image2}', '{image3}', '{image4}', '{image5}', '{image6}', '{image7}', '{image8}', '{image9}' ]
|
||||
CLEAN: whitespace
|
||||
USE_GRAD: False
|
||||
#
|
||||
MODEL_LOCAL:
|
||||
NAME: LatentDiffusionACE
|
||||
PRETRAINED_MODEL:
|
||||
IGNORE_KEYS: [ ]
|
||||
SCALE_FACTOR: 0.18215
|
||||
SIZE_FACTOR: 8
|
||||
DECODER_BIAS: 0.5
|
||||
DEFAULT_N_PROMPT: ""
|
||||
TEXT_IDENTIFIER: [ '{image}', '{image1}', '{image2}', '{image3}', '{image4}', '{image5}', '{image6}', '{image7}', '{image8}', '{image9}' ]
|
||||
USE_TEXT_POS_EMBEDDINGS: True
|
||||
#
|
||||
DIFFUSION:
|
||||
NAME: BaseDiffusion
|
||||
PREDICTION_TYPE: eps
|
||||
MIN_SNR_GAMMA:
|
||||
NOISE_SCHEDULER:
|
||||
NAME: LinearScheduler
|
||||
NUM_TIMESTEPS: 1000
|
||||
BETA_MIN: 0.0001
|
||||
BETA_MAX: 0.02
|
||||
#
|
||||
DIFFUSION_MODEL:
|
||||
NAME: ACE
|
||||
PRETRAINED_MODEL: models/scepter/ACE-0.6B-512px/models/dit/ace_0.6b_512px.pth
|
||||
IGNORE_KEYS: [ ]
|
||||
PATCH_SIZE: 2
|
||||
IN_CHANNELS: 4
|
||||
HIDDEN_SIZE: 1152
|
||||
DEPTH: 28
|
||||
NUM_HEADS: 16
|
||||
MLP_RATIO: 4.0
|
||||
PRED_SIGMA: True
|
||||
DROP_PATH: 0.0
|
||||
WINDOW_DIZE: 0
|
||||
Y_CHANNELS: 4096
|
||||
MAX_SEQ_LEN: 1024
|
||||
QK_NORM: True
|
||||
USE_GRAD_CHECKPOINT: True
|
||||
ATTENTION_BACKEND: flash_attn
|
||||
#
|
||||
FIRST_STAGE_MODEL:
|
||||
NAME: AutoencoderKL
|
||||
EMBED_DIM: 4
|
||||
PRETRAINED_MODEL: models/scepter/ACE-0.6B-512px/models/vae/vae.bin
|
||||
IGNORE_KEYS: []
|
||||
#
|
||||
ENCODER:
|
||||
NAME: Encoder
|
||||
CH: 128
|
||||
OUT_CH: 3
|
||||
NUM_RES_BLOCKS: 2
|
||||
IN_CHANNELS: 3
|
||||
ATTN_RESOLUTIONS: [ ]
|
||||
CH_MULT: [ 1, 2, 4, 4 ]
|
||||
Z_CHANNELS: 4
|
||||
DOUBLE_Z: True
|
||||
DROPOUT: 0.0
|
||||
RESAMP_WITH_CONV: True
|
||||
#
|
||||
DECODER:
|
||||
NAME: Decoder
|
||||
CH: 128
|
||||
OUT_CH: 3
|
||||
NUM_RES_BLOCKS: 2
|
||||
IN_CHANNELS: 3
|
||||
ATTN_RESOLUTIONS: [ ]
|
||||
CH_MULT: [ 1, 2, 4, 4 ]
|
||||
Z_CHANNELS: 4
|
||||
DROPOUT: 0.0
|
||||
RESAMP_WITH_CONV: True
|
||||
GIVE_PRE_END: False
|
||||
TANH_OUT: False
|
||||
#
|
||||
COND_STAGE_MODEL:
|
||||
NAME: T5EmbedderHF
|
||||
PRETRAINED_MODEL: models/scepter/ACE-0.6B-512px/models/text_encoder/t5-v1_1-xxl/
|
||||
TOKENIZER_PATH: models/scepter/ACE-0.6B-512px/models/tokenizer/t5-v1_1-xxl
|
||||
LENGTH: 120
|
||||
T5_DTYPE: bfloat16
|
||||
ADDED_IDENTIFIER: [ '{image}', '{caption}', '{mask}', '{ref_image}', '{image1}', '{image2}', '{image3}', '{image4}', '{image5}', '{image6}', '{image7}', '{image8}', '{image9}' ]
|
||||
CLEAN: whitespace
|
||||
USE_GRAD: False
|
||||
#
|
||||
MODEL_HF:
|
||||
NAME: LatentDiffusionACE
|
||||
PRETRAINED_MODEL:
|
||||
IGNORE_KEYS: [ ]
|
||||
SCALE_FACTOR: 0.18215
|
||||
SIZE_FACTOR: 8
|
||||
DECODER_BIAS: 0.5
|
||||
DEFAULT_N_PROMPT: ""
|
||||
TEXT_IDENTIFIER: [ '{image}', '{image1}', '{image2}', '{image3}', '{image4}', '{image5}', '{image6}', '{image7}', '{image8}', '{image9}' ]
|
||||
USE_TEXT_POS_EMBEDDINGS: True
|
||||
#
|
||||
DIFFUSION:
|
||||
NAME: BaseDiffusion
|
||||
PREDICTION_TYPE: eps
|
||||
MIN_SNR_GAMMA:
|
||||
NOISE_SCHEDULER:
|
||||
NAME: LinearScheduler
|
||||
NUM_TIMESTEPS: 1000
|
||||
BETA_MIN: 0.0001
|
||||
BETA_MAX: 0.02
|
||||
#
|
||||
DIFFUSION_MODEL:
|
||||
NAME: ACE
|
||||
PRETRAINED_MODEL: hf://scepter-studio/ACE-0.6B-512px@models/dit/ace_0.6b_512px.pth
|
||||
IGNORE_KEYS: [ ]
|
||||
PATCH_SIZE: 2
|
||||
IN_CHANNELS: 4
|
||||
HIDDEN_SIZE: 1152
|
||||
DEPTH: 28
|
||||
NUM_HEADS: 16
|
||||
MLP_RATIO: 4.0
|
||||
PRED_SIGMA: True
|
||||
DROP_PATH: 0.0
|
||||
WINDOW_DIZE: 0
|
||||
Y_CHANNELS: 4096
|
||||
MAX_SEQ_LEN: 1024
|
||||
QK_NORM: True
|
||||
USE_GRAD_CHECKPOINT: True
|
||||
ATTENTION_BACKEND: flash_attn
|
||||
#
|
||||
FIRST_STAGE_MODEL:
|
||||
NAME: AutoencoderKL
|
||||
EMBED_DIM: 4
|
||||
PRETRAINED_MODEL: hf://scepter-studio/ACE-0.6B-512px@models/vae/vae.bin
|
||||
IGNORE_KEYS: []
|
||||
#
|
||||
ENCODER:
|
||||
NAME: Encoder
|
||||
CH: 128
|
||||
OUT_CH: 3
|
||||
NUM_RES_BLOCKS: 2
|
||||
IN_CHANNELS: 3
|
||||
ATTN_RESOLUTIONS: [ ]
|
||||
CH_MULT: [ 1, 2, 4, 4 ]
|
||||
Z_CHANNELS: 4
|
||||
DOUBLE_Z: True
|
||||
DROPOUT: 0.0
|
||||
RESAMP_WITH_CONV: True
|
||||
#
|
||||
DECODER:
|
||||
NAME: Decoder
|
||||
CH: 128
|
||||
OUT_CH: 3
|
||||
NUM_RES_BLOCKS: 2
|
||||
IN_CHANNELS: 3
|
||||
ATTN_RESOLUTIONS: [ ]
|
||||
CH_MULT: [ 1, 2, 4, 4 ]
|
||||
Z_CHANNELS: 4
|
||||
DROPOUT: 0.0
|
||||
RESAMP_WITH_CONV: True
|
||||
GIVE_PRE_END: False
|
||||
TANH_OUT: False
|
||||
#
|
||||
COND_STAGE_MODEL:
|
||||
NAME: T5EmbedderHF
|
||||
PRETRAINED_MODEL: hf://scepter-studio/ACE-0.6B-512px@models/text_encoder/t5-v1_1-xxl/
|
||||
TOKENIZER_PATH: hf://scepter-studio/ACE-0.6B-512px@models/tokenizer/t5-v1_1-xxl
|
||||
LENGTH: 120
|
||||
T5_DTYPE: bfloat16
|
||||
ADDED_IDENTIFIER: [ '{image}', '{caption}', '{mask}', '{ref_image}', '{image1}', '{image2}', '{image3}', '{image4}', '{image5}', '{image6}', '{image7}', '{image8}', '{image9}' ]
|
||||
CLEAN: whitespace
|
||||
USE_GRAD: False
|
||||
@@ -53,6 +53,12 @@ BASE_MODELS:
|
||||
FIRST_STAGE_MODEL: FLUX1.0_SCHNELL_AutoencoderKLFlux
|
||||
COND_STAGE_MODEL: FLUX1.0_SCHNELL_T5PlusClipFluxEmbedder
|
||||
CONFIG: config/flux1.0_schnell_pro.yaml
|
||||
-
|
||||
NAME: ACE_0.6B_512
|
||||
DIFFUSION_MODEL: ACE_0.6B_512_ACE
|
||||
FIRST_STAGE_MODEL: ACE_0.6B_512_AutoencoderKL
|
||||
COND_STAGE_MODEL: ACE_0.6B_512_T5EmbedderHF
|
||||
CONFIG: config/ace_0.6b_512_pro.yaml
|
||||
|
||||
MODEL_SOURCE:
|
||||
- "ModelScope"
|
||||
|
||||
@@ -4,8 +4,12 @@ import copy
|
||||
import logging
|
||||
import os
|
||||
|
||||
import torch
|
||||
import torchvision.transforms as TT
|
||||
|
||||
from .constant import WORKFLOW_CONFIG, WORKFLOW_MODEL_PREFIX
|
||||
|
||||
|
||||
class ModelNode:
|
||||
def __init__(self):
|
||||
from scepter.modules.utils.logger import get_logger
|
||||
@@ -22,7 +26,7 @@ class ModelNode:
|
||||
return {
|
||||
'required': {
|
||||
'model': (list(s().model_file.keys()), ),
|
||||
"model_source": (list(s().cfg['MODEL_SOURCE']), ),
|
||||
'model_source': (list(s().cfg['MODEL_SOURCE']), ),
|
||||
'prompt': ('STRING', {
|
||||
'multiline': True
|
||||
}),
|
||||
@@ -34,7 +38,9 @@ class ModelNode:
|
||||
'parameters': ('CONDITIONING', ),
|
||||
'mantras': ('CONDITIONING', ),
|
||||
'tuners': ('CONDITIONING', ),
|
||||
'controls': ('CONDITIONING', )
|
||||
'controls': ('CONDITIONING', ),
|
||||
'image': ('IMAGE',),
|
||||
'mask': ('MASK',)
|
||||
}
|
||||
}
|
||||
|
||||
@@ -51,24 +57,34 @@ class ModelNode:
|
||||
parameters=None,
|
||||
mantras=None,
|
||||
tuners=None,
|
||||
controls=None):
|
||||
controls=None,
|
||||
image=None,
|
||||
mask=None):
|
||||
if image is not None:
|
||||
image = [TT.ToPILImage()(image.squeeze(0).permute(2, 0, 1))]
|
||||
if mask is not None:
|
||||
mask = [TT.ToPILImage()(mask.squeeze(0))]
|
||||
data = self.format_parameters(model, model_source, prompt, negative_prompt,
|
||||
parameters, mantras, tuners, controls)
|
||||
parameters, mantras, tuners, controls, image, mask)
|
||||
cfg = self.model_file.get(model)['config']
|
||||
cfg = self.source_mapping(cfg, model_source)
|
||||
self.init_infer(model, cfg)
|
||||
output = self.diff_infer(data[0], **data[1])
|
||||
|
||||
x = output['images'].permute(0, 2, 3, 1)
|
||||
output_image = x.unsqueeze(0)
|
||||
|
||||
if model.startswith('ACE'):
|
||||
output = self.diff_infer(**data[0], **data[1])
|
||||
output_image = torch.stack([ TT.ToTensor()(img) for img in output]).permute(0, 2, 3, 1).unsqueeze(0)
|
||||
else:
|
||||
output = self.diff_infer(data[0], **data[1])
|
||||
x = output['images'].permute(0, 2, 3, 1)
|
||||
output_image = x.unsqueeze(0) # torch.Size([1, 1, 1024, 1024, 3])
|
||||
return output_image
|
||||
|
||||
def source_mapping(self, cfg, source, type='model'):
|
||||
def mapping(str):
|
||||
if source == "Local":
|
||||
str = os.path.join(WORKFLOW_MODEL_PREFIX, str.split('/', 3)[-1].replace('@', '/'))
|
||||
elif source == "HuggingFace":
|
||||
if source == 'Local':
|
||||
str = os.path.join(WORKFLOW_MODEL_PREFIX,
|
||||
str.split('/', 3)[-1].replace('@', '/'))
|
||||
elif source == 'HuggingFace':
|
||||
str = str.replace('ms://iic/', 'hf://scepter-studio/')
|
||||
return str
|
||||
|
||||
@@ -84,7 +100,7 @@ class ModelNode:
|
||||
cfg_new.MODEL = cfg_new.MODEL_HF
|
||||
return cfg_new
|
||||
else:
|
||||
raise NotImplementedError(f"Unknown model source: {source}")
|
||||
raise NotImplementedError(f'Unknown model source: {source}')
|
||||
elif type in ['mantra', 'tuner', 'control']:
|
||||
if 'MODEL_PATH' in cfg and cfg.MODEL_PATH is not None:
|
||||
cfg.MODEL_PATH = mapping(cfg.MODEL_PATH)
|
||||
@@ -92,13 +108,14 @@ class ModelNode:
|
||||
cfg.IMAGE_PATH = mapping(cfg.IMAGE_PATH)
|
||||
return cfg
|
||||
else:
|
||||
raise NotImplementedError(f"Unknown model source: {source}")
|
||||
raise NotImplementedError(f'Unknown model source: {source}')
|
||||
|
||||
def init_infer(self, model_name, cfg):
|
||||
from scepter.modules.inference.diffusion_inference import DiffusionInference
|
||||
from scepter.modules.inference.sd3_inference import SD3Inference
|
||||
from scepter.modules.inference.pixart_inference import PixArtInference
|
||||
from scepter.modules.inference.flux_inference import FluxInference
|
||||
from scepter.modules.inference.ace_inference import ACEInference
|
||||
|
||||
if model_name.startswith('PIXART'):
|
||||
infer_func = PixArtInference
|
||||
@@ -106,6 +123,8 @@ class ModelNode:
|
||||
infer_func = SD3Inference
|
||||
elif model_name.startswith('FLUX'):
|
||||
infer_func = FluxInference
|
||||
elif model_name.startswith('ACE'):
|
||||
infer_func = ACEInference
|
||||
else:
|
||||
infer_func = DiffusionInference
|
||||
|
||||
@@ -132,33 +151,44 @@ class ModelNode:
|
||||
parameters,
|
||||
mantras,
|
||||
tuners,
|
||||
controls):
|
||||
controls,
|
||||
image,
|
||||
mask):
|
||||
input_data = {'prompt': prompt, 'negative_prompt': negative_prompt}
|
||||
input_params = {
|
||||
'diffusion_model': self.model_file.get(model)['diffusion_model'],
|
||||
'first_stage_model': self.model_file.get(model)['first_stage_model'],
|
||||
'first_stage_model':
|
||||
self.model_file.get(model)['first_stage_model'],
|
||||
'cond_stage_model': self.model_file.get(model)['cond_stage_model']
|
||||
}
|
||||
|
||||
if image is not None:
|
||||
input_data.update({"image": image})
|
||||
|
||||
if mask is not None:
|
||||
input_data.update({"mask": mask})
|
||||
|
||||
if parameters:
|
||||
seed = parameters.get('seed', -1)
|
||||
seed = parameters.pop('seed', -1)
|
||||
input_params.update({'seed': seed})
|
||||
input_data.update(parameters)
|
||||
|
||||
if mantras:
|
||||
prompt_template = mantras['prompt_template']
|
||||
negative_prompt_template = mantras['negative_prompt_template']
|
||||
if prompt_template != "":
|
||||
if prompt_template != '':
|
||||
prompt = prompt_template.replace('{prompt}', prompt)
|
||||
if negative_prompt_template != "":
|
||||
negative_prompt = negative_prompt + ',' + negative_prompt_template if negative_prompt != "" else negative_prompt_template
|
||||
if negative_prompt_template != '':
|
||||
negative_prompt = negative_prompt + ',' + negative_prompt_template if negative_prompt != '' else negative_prompt_template
|
||||
input_data['prompt'] = prompt
|
||||
input_data['negative_prompt'] = negative_prompt
|
||||
input_params.update({'mantra_state': True})
|
||||
|
||||
if tuners:
|
||||
tuner_info = tuners['tuner_info']
|
||||
tuner_info = self.source_mapping(tuner_info, model_source, type='tuner')
|
||||
tuner_info = self.source_mapping(tuner_info,
|
||||
model_source,
|
||||
type='tuner')
|
||||
tuner_scale = tuners['tuner_scale']
|
||||
assert model == tuner_info['BASE_MODEL'], (
|
||||
'The tuner model is inconsistent with the base model, '
|
||||
@@ -170,7 +200,8 @@ class ModelNode:
|
||||
})
|
||||
|
||||
if controls:
|
||||
controls['control_model'] = self.source_mapping(controls['control_model'], model_source, type='control')
|
||||
controls['control_model'] = self.source_mapping(
|
||||
controls['control_model'], model_source, type='control')
|
||||
assert model == controls['control_model']['BASE_MODEL'], (
|
||||
'The control model is inconsistent with the base model, '
|
||||
'please ensure that the selected model is consistent')
|
||||
|
||||
@@ -8,16 +8,18 @@ import numpy as np
|
||||
import torchvision.transforms as TT
|
||||
import torchvision.transforms.functional as TF
|
||||
from PIL import Image
|
||||
from torchvision.utils import save_image
|
||||
|
||||
from scepter.modules.annotator.registry import ANNOTATORS
|
||||
from scepter.modules.inference.ace_inference import ACEInference
|
||||
from scepter.modules.inference.diffusion_inference import DiffusionInference
|
||||
from scepter.modules.inference.sd3_inference import SD3Inference
|
||||
from scepter.modules.inference.flux_inference import FluxInference
|
||||
from scepter.modules.inference.sd3_inference import SD3Inference
|
||||
from scepter.modules.inference.stylebooth_inference import StyleboothInference
|
||||
from scepter.modules.utils.config import Config
|
||||
from scepter.modules.utils.distribute import we
|
||||
from scepter.modules.utils.file_system import FS
|
||||
from scepter.modules.utils.logger import get_logger
|
||||
from torchvision.utils import save_image
|
||||
|
||||
|
||||
class DiffusionInferenceTest(unittest.TestCase):
|
||||
@@ -241,19 +243,28 @@ class DiffusionInferenceTest(unittest.TestCase):
|
||||
save_image(output['images'], save_path)
|
||||
print(save_path)
|
||||
|
||||
# @unittest.skip('')
|
||||
@unittest.skip('')
|
||||
def test_flux(self):
|
||||
config_file = 'scepter/methods/studio/inference/dit/flux1.0_dev_pro.yaml'
|
||||
cfg = Config(cfg_file=config_file)
|
||||
diff_infer = FluxInference(logger=self.logger)
|
||||
diff_infer.init_from_cfg(cfg)
|
||||
output = diff_infer({
|
||||
'prompt': '1 girl',
|
||||
'seed': 2024
|
||||
})
|
||||
output = diff_infer({'prompt': '1 girl', 'seed': 2024})
|
||||
save_path = os.path.join(self.tmp_dir, 'flux_dev_1girl.png')
|
||||
save_image(output['images'], save_path)
|
||||
print(save_path)
|
||||
|
||||
# @unittest.skip('')
|
||||
def test_ace(self):
|
||||
config_file = 'scepter/methods/studio/chatbot/models/ace_0.6b_512.yaml'
|
||||
cfg = Config(cfg_file=config_file)
|
||||
diff_infer = ACEInference(logger=self.logger)
|
||||
diff_infer.init_from_cfg(cfg)
|
||||
output = diff_infer(prompt='1 girl', seed=2024)
|
||||
save_path = os.path.join(self.tmp_dir, 'ace_1girl.png')
|
||||
output[0].save(save_path, format='PNG')
|
||||
print(save_path)
|
||||
|
||||
|
||||
if __name__ == '__main__':
|
||||
unittest.main()
|
||||
|
||||
Reference in New Issue
Block a user