Compare commits
9
Commits
v1.2.9_dev
...
v1.4.0_dev
| Author | SHA1 | Date | |
|---|---|---|---|
 jiangzeyinzi |
c4b4d88e75 | ||
|
jiangzeyinzi
|
043222de49 | ||
|
皓童
|
d7dbdc5292 | ||
|
mcj
|
711c10a68c | ||
|
jiangzeyinzi
|
adda36e39d | ||
|
jiangzeyinzi
|
1da1864993 | ||
|
Great
|
5eac362325 | ||
|
Great
|
9ae3bca43d | ||
|
jiangzeyinzi
|
ca034ef765 |
@@ -0,0 +1,184 @@
|
|||||||
|
<p align="center">
|
||||||
|
|
||||||
|
<h2 align="center"><img src="https://raw.githubusercontent.com/ali-vilab/ACE/refs/heads/main/assets/figures/icon.png" height=16> : All-round Creator and Editor Following <br> Instructions via Diffusion Transformer</h2>
|
||||||
|
|
||||||
|
<p align="center">
|
||||||
|
<a href="https://arxiv.org/abs/2410.00086"><img src='https://img.shields.io/badge/arXiv-ACE-red' alt='Paper PDF'></a>
|
||||||
|
<a href='https://ali-vilab.github.io/ace-page'><img src='https://img.shields.io/badge/Project_Page-ACE-blue' alt='Project Page'></a>
|
||||||
|
<a href='https://github.com/modelscope/scepter'><img src='https://img.shields.io/badge/Scepter-ACE-green'></a>
|
||||||
|
<a href='https://huggingface.co/spaces/scepter-studio/ACE-Chat'><img src='https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Space-orange'></a>
|
||||||
|
<a href='https://huggingface.co/scepter-studio/ACE-0.6B-512px'><img src='https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Model-orange'></a>
|
||||||
|
<a href='https://www.modelscope.cn/models/iic/ACE-0.6B-512px'><img src='https://img.shields.io/badge/ModelScope-Model-purple'></a>
|
||||||
|
<br>
|
||||||
|
<strong>Zhen Han*</strong>
|
||||||
|
·
|
||||||
|
<strong>Zeyinzi Jiang*</strong>
|
||||||
|
·
|
||||||
|
<strong>Yulin Pan*</strong>
|
||||||
|
·
|
||||||
|
<strong>Jingfeng Zhang*</strong>
|
||||||
|
·
|
||||||
|
<strong>Chaojie Mao*</strong>
|
||||||
|
<br>
|
||||||
|
<strong>Chenwei Xie</strong>
|
||||||
|
·
|
||||||
|
<strong>Yu Liu</strong>
|
||||||
|
·
|
||||||
|
<strong>Jingren Zhou</strong>
|
||||||
|
<br>
|
||||||
|
Tongyi Lab, Alibaba Group
|
||||||
|
</p>
|
||||||
|
<table align="center">
|
||||||
|
<tr>
|
||||||
|
<td>
|
||||||
|
<img src="https://raw.githubusercontent.com/ali-vilab/ACE/refs/heads/main/assets/figures/teaser.png">
|
||||||
|
</td>
|
||||||
|
</tr>
|
||||||
|
</table>
|
||||||
|
|
||||||
|
|
||||||
|
## 🚀 Installation
|
||||||
|
Install the necessary packages with `pip`:
|
||||||
|
```bash
|
||||||
|
pip install -r requirements.txt
|
||||||
|
```
|
||||||
|
|
||||||
|
## 🔥 ACE Models
|
||||||
|
| **Model** | **Status** |
|
||||||
|
|:----------------:|:---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------:|
|
||||||
|
| ACE-0.6B-512px | [](https://huggingface.co/spaces/scepter-studio/ACE-Chat)<br>[](https://www.modelscope.cn/models/iic/ACE-0.6B-512px) [](https://huggingface.co/scepter-studio/ACE-0.6B-512px) |
|
||||||
|
| ACE-0.6B-1024px | [](https://huggingface.co/spaces/scepter-studio/ACE-Refiner-Chat)<br>[](https://www.modelscope.cn/models/iic/ACE-0.6B-1024px) [](https://huggingface.co/scepter-studio/ACE-0.6B-1024px) | |
|
||||||
|
## 🖼 Model Performance Visualization
|
||||||
|
|
||||||
|
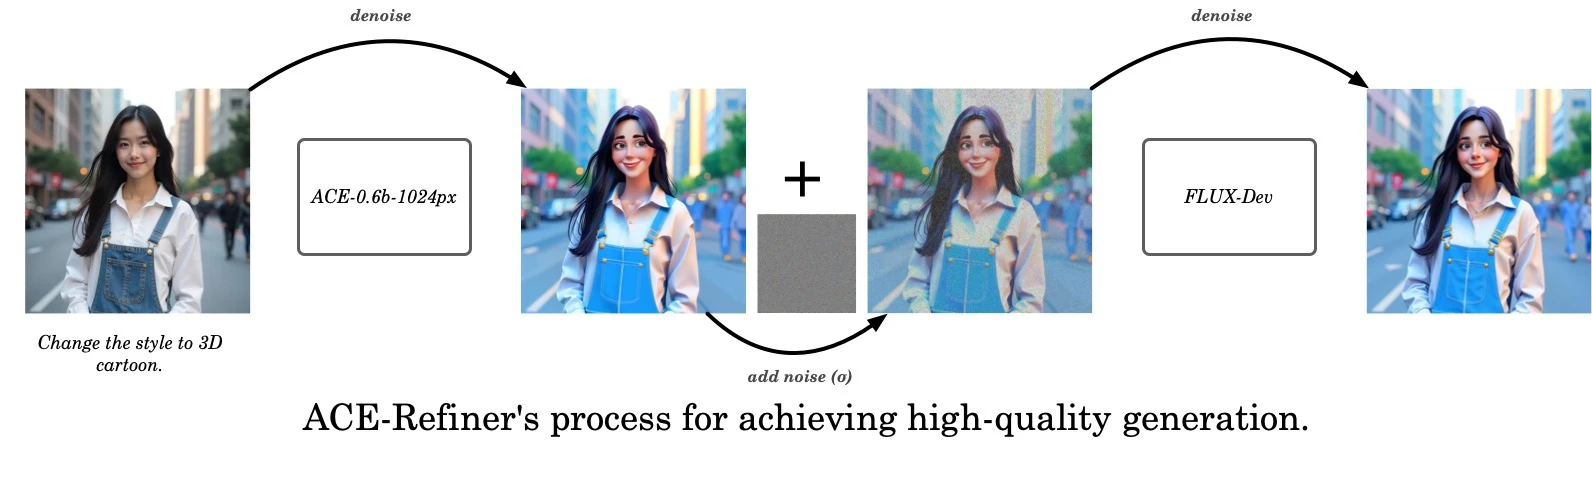
The current model's parameters scale of ACE is 0.6B, which imposes certain limitations on the quality of image generation. [FLUX.1-Dev](https://huggingface.co/black-forest-labs/FLUX.1-dev), on the other hand,
|
||||||
|
has a significant advantage in text-to-image generation quality. By using SDEdit, we can effectively leverage the generative capabilities of FLUX to further enhance the image results generated by ACE. Based on the above considerations, we have designed the ACE-Refiner pipeline, as shown in the diagram below.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
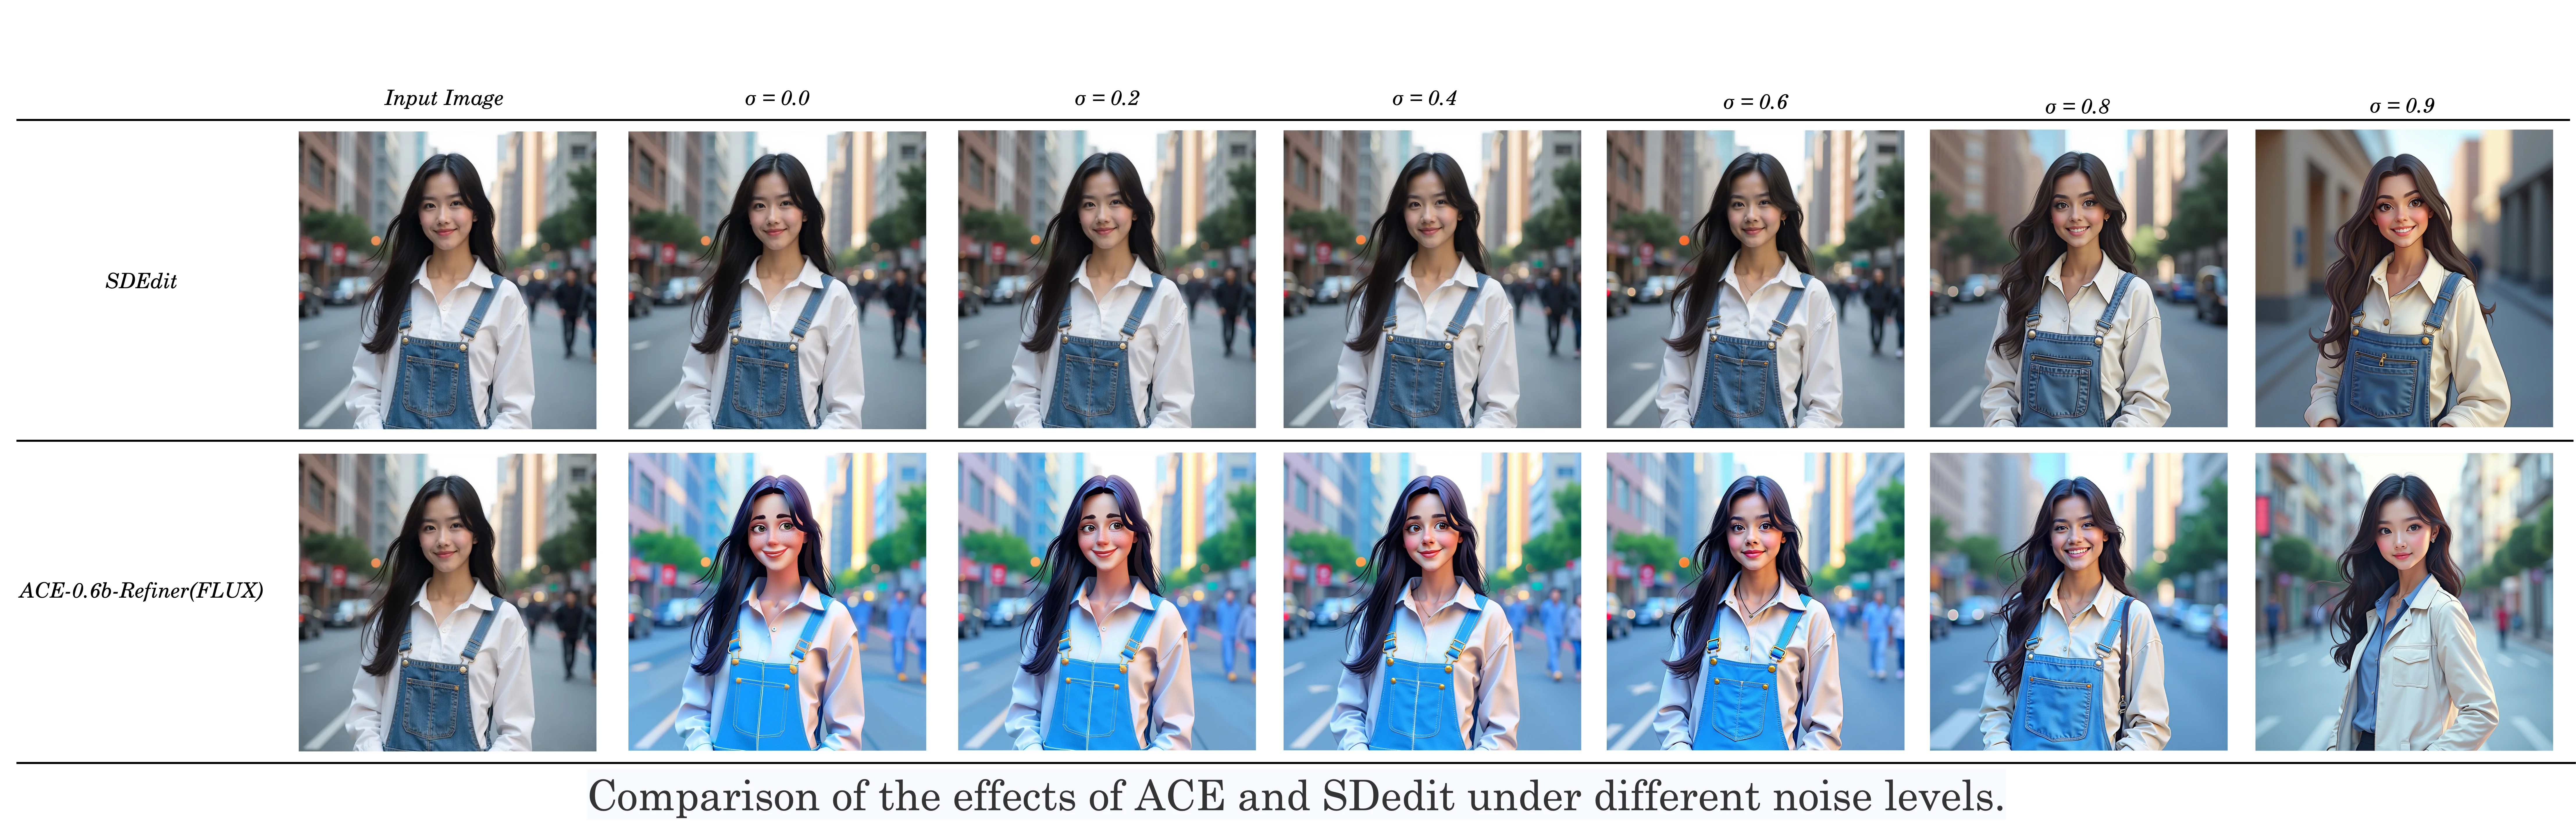
As shown in the figure below, when the strength
|
||||||
|
σ of the generated image is high, the generated image will suffer from fidelity loss compared to the original image. Conversely, lower
|
||||||
|
σ does not significantly improve the image quality. Therefore, users can make a trade-off between fidelity to the generated result and the image quality based on their own needs.
|
||||||
|
Users can set the value of "REFINER_SCALE" in the configuration file `config/inference_config/models/ace_0.6b_1024_refiner.yaml`.
|
||||||
|
We recommend that users use the advance options in the [webui-demo](#-chat-bot-) for effect verification.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
We compared the generation and editing performance of different models on several tasks, as shown as following.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
## 🔥 Training
|
||||||
|
|
||||||
|
We offer a demonstration training YAML that enables the end-to-end training of ACE using a toy dataset. For a comprehensive overview of the hyperparameter configurations, please consult `config/ace_0.6b_512_train.yaml`.
|
||||||
|
|
||||||
|
### Prepare datasets
|
||||||
|
|
||||||
|
Please find the dataset class located in `modules/data/dataset/dataset.py`,
|
||||||
|
designed to facilitate end-to-end training using an open-source toy dataset.
|
||||||
|
Download a dataset zip file from [modelscope](https://www.modelscope.cn/models/iic/scepter/resolve/master/datasets/hed_pair.zip), and then extract its contents into the `cache/datasets/` directory.
|
||||||
|
|
||||||
|
Should you wish to prepare your own datasets, we recommend consulting `modules/data/dataset/dataset.py` for detailed guidance on the required data format.
|
||||||
|
|
||||||
|
### Prepare initial weight
|
||||||
|
The ACE checkpoint has been uploaded to both ModelScope and HuggingFace platforms:
|
||||||
|
* [ModelScope](https://www.modelscope.cn/models/iic/ACE-0.6B-512px)
|
||||||
|
* [HuggingFace](https://huggingface.co/scepter-studio/ACE-0.6B-512px)
|
||||||
|
|
||||||
|
In the provided training YAML configuration, we have designated the Modelscope URL as the default checkpoint URL. Should you wish to transition to Hugging Face, you can effortlessly achieve this by modifying the PRETRAINED_MODEL value within the YAML file (replace the prefix "ms://iic" to "hf://scepter-studio").
|
||||||
|
|
||||||
|
|
||||||
|
### Start training
|
||||||
|
|
||||||
|
You can easily start training procedure by executing the following command:
|
||||||
|
```bash
|
||||||
|
# ACE-0.6B-512px
|
||||||
|
PYTHONPATH=. python tools/run_train.py --cfg config/ace_0.6b_512_train.yaml
|
||||||
|
# ACE-0.6B-1024px
|
||||||
|
PYTHONPATH=. python tools/run_train.py --cfg config/ace_0.6b_1024_train.yaml
|
||||||
|
```
|
||||||
|
|
||||||
|
## 🚀 Inference
|
||||||
|
|
||||||
|
We provide a simple inference demo that allows users to generate images from text descriptions.
|
||||||
|
```bash
|
||||||
|
PYTHONPATH=. python tools/run_inference.py --cfg config/inference_config/models/ace_0.6b_512.yaml --instruction "make the boy cry, his eyes filled with tears" --seed 199999 --input_image examples/input_images/example0.webp
|
||||||
|
```
|
||||||
|
We recommend runing the examples for quick testing. Running the following command will run the example inference and the results will be saved in `examples/output_images/`.
|
||||||
|
```bash
|
||||||
|
PYTHONPATH=. python tools/run_inference.py --cfg config/inference_config/models/ace_0.6b_512.yaml
|
||||||
|
```
|
||||||
|
|
||||||
|
## 💬 Chat Bot
|
||||||
|
We have developed an chatbot UI utilizing Gradio, designed to transform user input in natural language into visually stunning images that align semantically with the provided instructions. Users can effortlessly initiate the chatbot app by executing the following command:
|
||||||
|
```bash
|
||||||
|
python chatbot/run_gradio.py --cfg chatbot/config/chatbot_ui.yaml --server_port 2024
|
||||||
|
```
|
||||||
|
|
||||||
|
<table align="center">
|
||||||
|
<tr>
|
||||||
|
<td>
|
||||||
|
<img src="https://raw.githubusercontent.com/ali-vilab/ACE/refs/heads/main/assets/videos/demo_chat.gif">
|
||||||
|
</td>
|
||||||
|
</tr>
|
||||||
|
</table>
|
||||||
|
|
||||||
|
## ⚙️️ ComfyUI Workflow
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
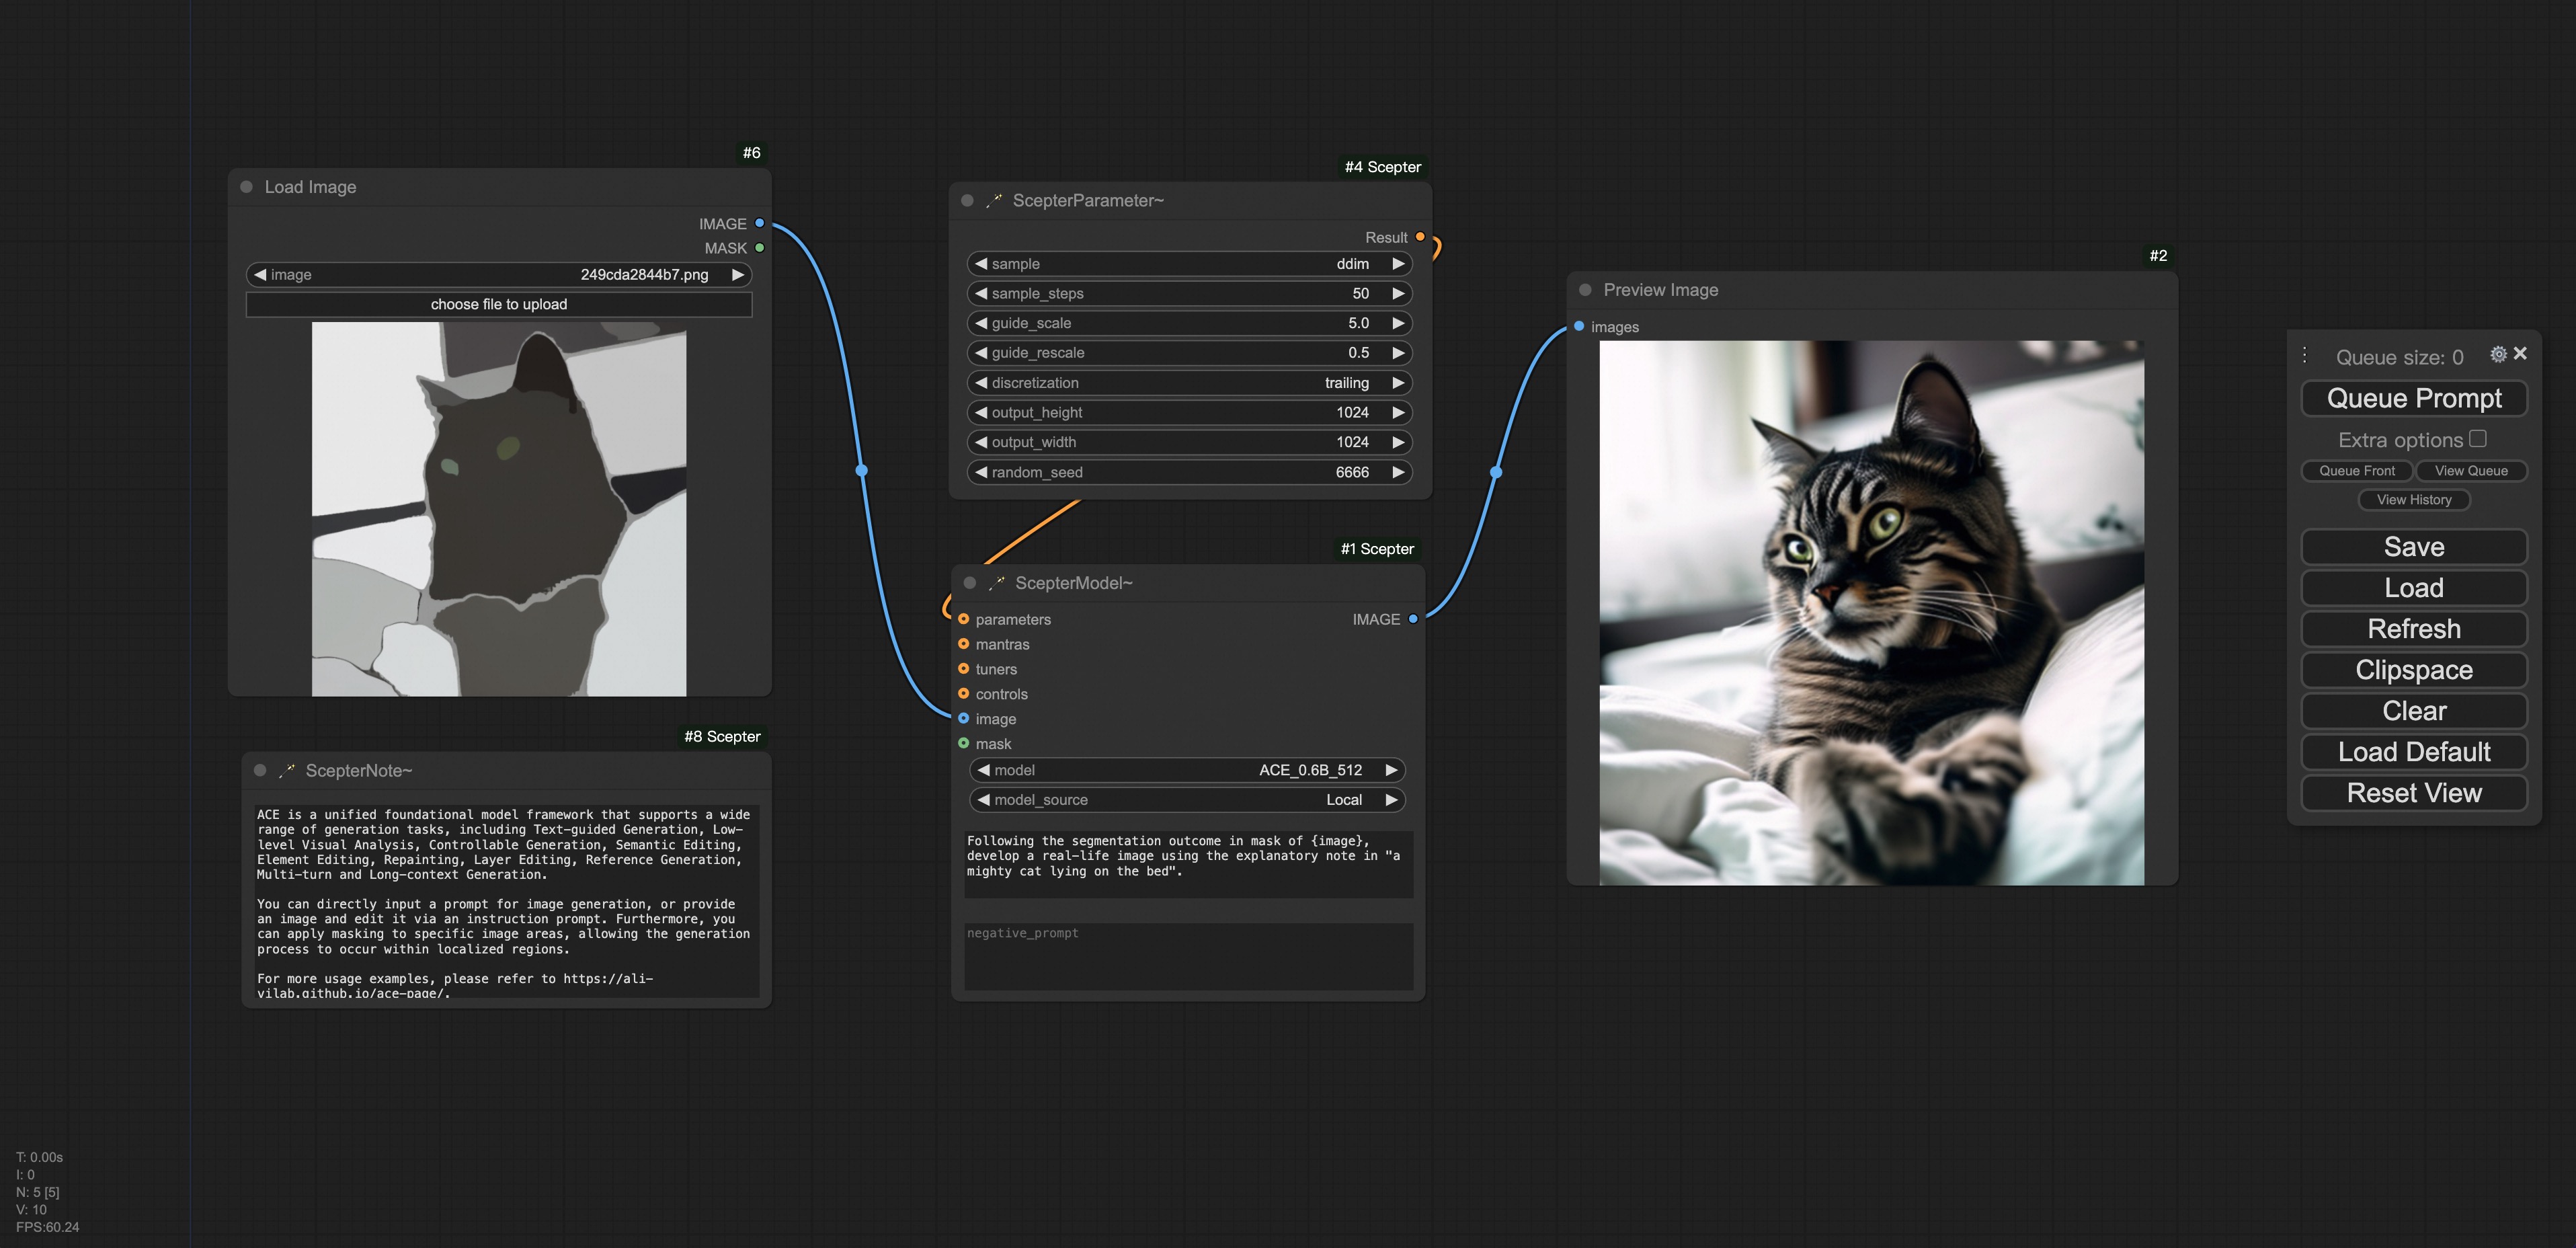
We support the use of ACE in the ComfyUI Workflow through the following methods:
|
||||||
|
|
||||||
|
1) Automatic installation directly via the ComfyUI Manager by searching for the **ComfyUI-Scepter** node.
|
||||||
|
2) Manually install by moving custom_nodes from Scepter to ComfyUI.
|
||||||
|
```shell
|
||||||
|
git clone https://github.com/modelscope/scepter.git
|
||||||
|
cd path/to/scepter
|
||||||
|
pip install -e .
|
||||||
|
cp -r path/to/scepter/workflow/ path/to/ComfyUI/custom_nodes/ComfyUI-Scepter
|
||||||
|
cd path/to/ComfyUI
|
||||||
|
python main.py
|
||||||
|
```
|
||||||
|
|
||||||
|
**Note**: You can use the nodes by dragging the sample images below into ComfyUI. Additionally, our nodes can automatically pull models from ModelScope or HuggingFace by selecting the *model_source* field, or you can place the already downloaded models in a local path.
|
||||||
|
|
||||||
|
<table><tbody>
|
||||||
|
<tr>
|
||||||
|
<th align="center" colspan="4">ACE Workflow Examples</th>
|
||||||
|
</tr>
|
||||||
|
<tr>
|
||||||
|
<th align="center" colspan="1">Control</th>
|
||||||
|
<th align="center" colspan="1">Semantic</th>
|
||||||
|
<th align="center" colspan="1">Element</th>
|
||||||
|
</tr>
|
||||||
|
<tr>
|
||||||
|
<td>
|
||||||
|
<a href="https://raw.githubusercontent.com/ali-vilab/ACE/refs/heads/main/assets/comfyui/ace_control.png" target="_blank">
|
||||||
|
<img src="https://raw.githubusercontent.com/ali-vilab/ACE/refs/heads/main/assets/comfyui/ace_control.png" width="200">
|
||||||
|
</a>
|
||||||
|
</td>
|
||||||
|
<td>
|
||||||
|
<a href="https://raw.githubusercontent.com/ali-vilab/ACE/refs/heads/main/assets/comfyui/ace_semantic.png" target="_blank">
|
||||||
|
<img src="https://raw.githubusercontent.com/ali-vilab/ACE/refs/heads/main/assets/comfyui/ace_semantic.png" width="200">
|
||||||
|
</a>
|
||||||
|
</td>
|
||||||
|
<td>
|
||||||
|
<a href="https://raw.githubusercontent.com/ali-vilab/ACE/refs/heads/main/assets/comfyui/ace_element.png" target="_blank">
|
||||||
|
<img src="https://raw.githubusercontent.com/ali-vilab/ACE/refs/heads/main/assets/comfyui/ace_element.png" width="200">
|
||||||
|
</a>
|
||||||
|
</td>
|
||||||
|
</tr>
|
||||||
|
</tbody>
|
||||||
|
</table>
|
||||||
|
|
||||||
|
|
||||||
|
## 📝 Citation
|
||||||
|
|
||||||
|
```bibtex
|
||||||
|
@article{han2024ace,
|
||||||
|
title={ACE: All-round Creator and Editor Following Instructions via Diffusion Transformer},
|
||||||
|
author={Han, Zhen and Jiang, Zeyinzi and Pan, Yulin and Zhang, Jingfeng and Mao, Chaojie and Xie, Chenwei and Liu, Yu and Zhou, Jingren},
|
||||||
|
journal={arXiv preprint arXiv:2410.00086},
|
||||||
|
year={2024}
|
||||||
|
}
|
||||||
|
```
|
||||||
@@ -18,10 +18,8 @@ SCEPTER offers 3 core components:
|
|||||||
|
|
||||||
|
|
||||||
## 🎉 News
|
## 🎉 News
|
||||||
- [🔥🔥🔥2024.11]: We're excited to announce the upcoming release of the [ACE-0.6b-1024px](https://huggingface.co/scepter-studio/ACE-0.6B-1024px) model,
|
- [🔥🔥🔥 2025.01]: We report ACE++, an instruction-based diffusion framework that tackles various image generation and editing tasks. The code and paper is available on [ACE++](https://ali-vilab.github.io/ACE_plus_page/).
|
||||||
which significantly enhances image generation quality compared with [ACE-0.6b-512px](https://huggingface.co/scepter-studio/ACE-0.6B-512px). The detailed documents can be found at [ACE repo](https://github.com/ali-vilab/ACE.git).
|
- [2024.11]: Supports video files, video annotation, caption translation in data management, and inference & training of the [CogVideoX](https://arxiv.org/abs/2408.06072).
|
||||||
At the same time, based on the editing results of ACE, combined with the powerful text-to-image capabilities of the [FLUX-dev](https://huggingface.co/black-forest-labs/FLUX.1-dev) model through SDEdit as an image quality refiner, the quality of image editing can be further enhanced.
|
|
||||||
- [🔥2024.11]: Supports video files, video annotation, caption translation in data management, and inference & training of the [CogVideoX](https://arxiv.org/abs/2408.06072).
|
|
||||||
- [2024.10]: We are pleased to announce the release of the code for [ACE](https://arxiv.org/abs/2410.00086), supporting Customized Training / Comfy UI Workflow / gradio-based ChatBot Interface.
|
- [2024.10]: We are pleased to announce the release of the code for [ACE](https://arxiv.org/abs/2410.00086), supporting Customized Training / Comfy UI Workflow / gradio-based ChatBot Interface.
|
||||||
- [2024.10]: Support for inference and tuning with [FLUX](https://huggingface.co/black-forest-labs/FLUX.1-dev), as well as for building [ComfyUI](https://github.com/comfyanonymous/ComfyUI) workflows using this framework.
|
- [2024.10]: Support for inference and tuning with [FLUX](https://huggingface.co/black-forest-labs/FLUX.1-dev), as well as for building [ComfyUI](https://github.com/comfyanonymous/ComfyUI) workflows using this framework.
|
||||||
- [2024.09]: We introduce **ACE**, an **A**ll-round **C**reator and **E**ditor adept at executing a diverse array of image editing tasks tailored to your specifications. Built upon the cutting-edge Diffusion Transformer architecture, ACE has been extensively trained on a comprehensive dataset to seamlessly interpret and execute any natural language instruction. For further information, please consult the [project page](https://ali-vilab.github.io/ace-page/).
|
||||||
@@ -35,123 +33,65 @@ At the same time, based on the editing results of ACE, combined with the powerfu
|
|||||||
- [2023.12]: We propose [SCEdit](https://arxiv.org/abs/2312.11392), an efficient and controllable generation framework.
|
- [2023.12]: We propose [SCEdit](https://arxiv.org/abs/2312.11392), an efficient and controllable generation framework.
|
||||||
- [2023.12]: We release [🪄SCEPTER](https://github.com/modelscope/scepter/) library.
|
- [2023.12]: We release [🪄SCEPTER](https://github.com/modelscope/scepter/) library.
|
||||||
|
|
||||||
|
[//]: # (## 🖼 Gallery for Recent Works)
|
||||||
|
|
||||||
|
[//]: # ()
|
||||||
|
[//]: # (### FLUX Tuners)
|
||||||
|
|
||||||
|
[//]: # ()
|
||||||
|
[//]: # (<table><tbody>)
|
||||||
|
|
||||||
## 🪄ACE
|
[//]: # ( <tr>)
|
||||||
|
|
||||||
ACE is a unified foundational model framework that supports a wide range of visual generation tasks. By defining CU for unifying multi-modal inputs across different tasks and incorporating long-context CU, we introduce historical contextual information into visual generation tasks, paving the way for ChatGPT-like dialog systems in visual generation.
|
[//]: # ( <th align="center" colspan="3">Yarn Style</th>)
|
||||||
|
|
||||||
[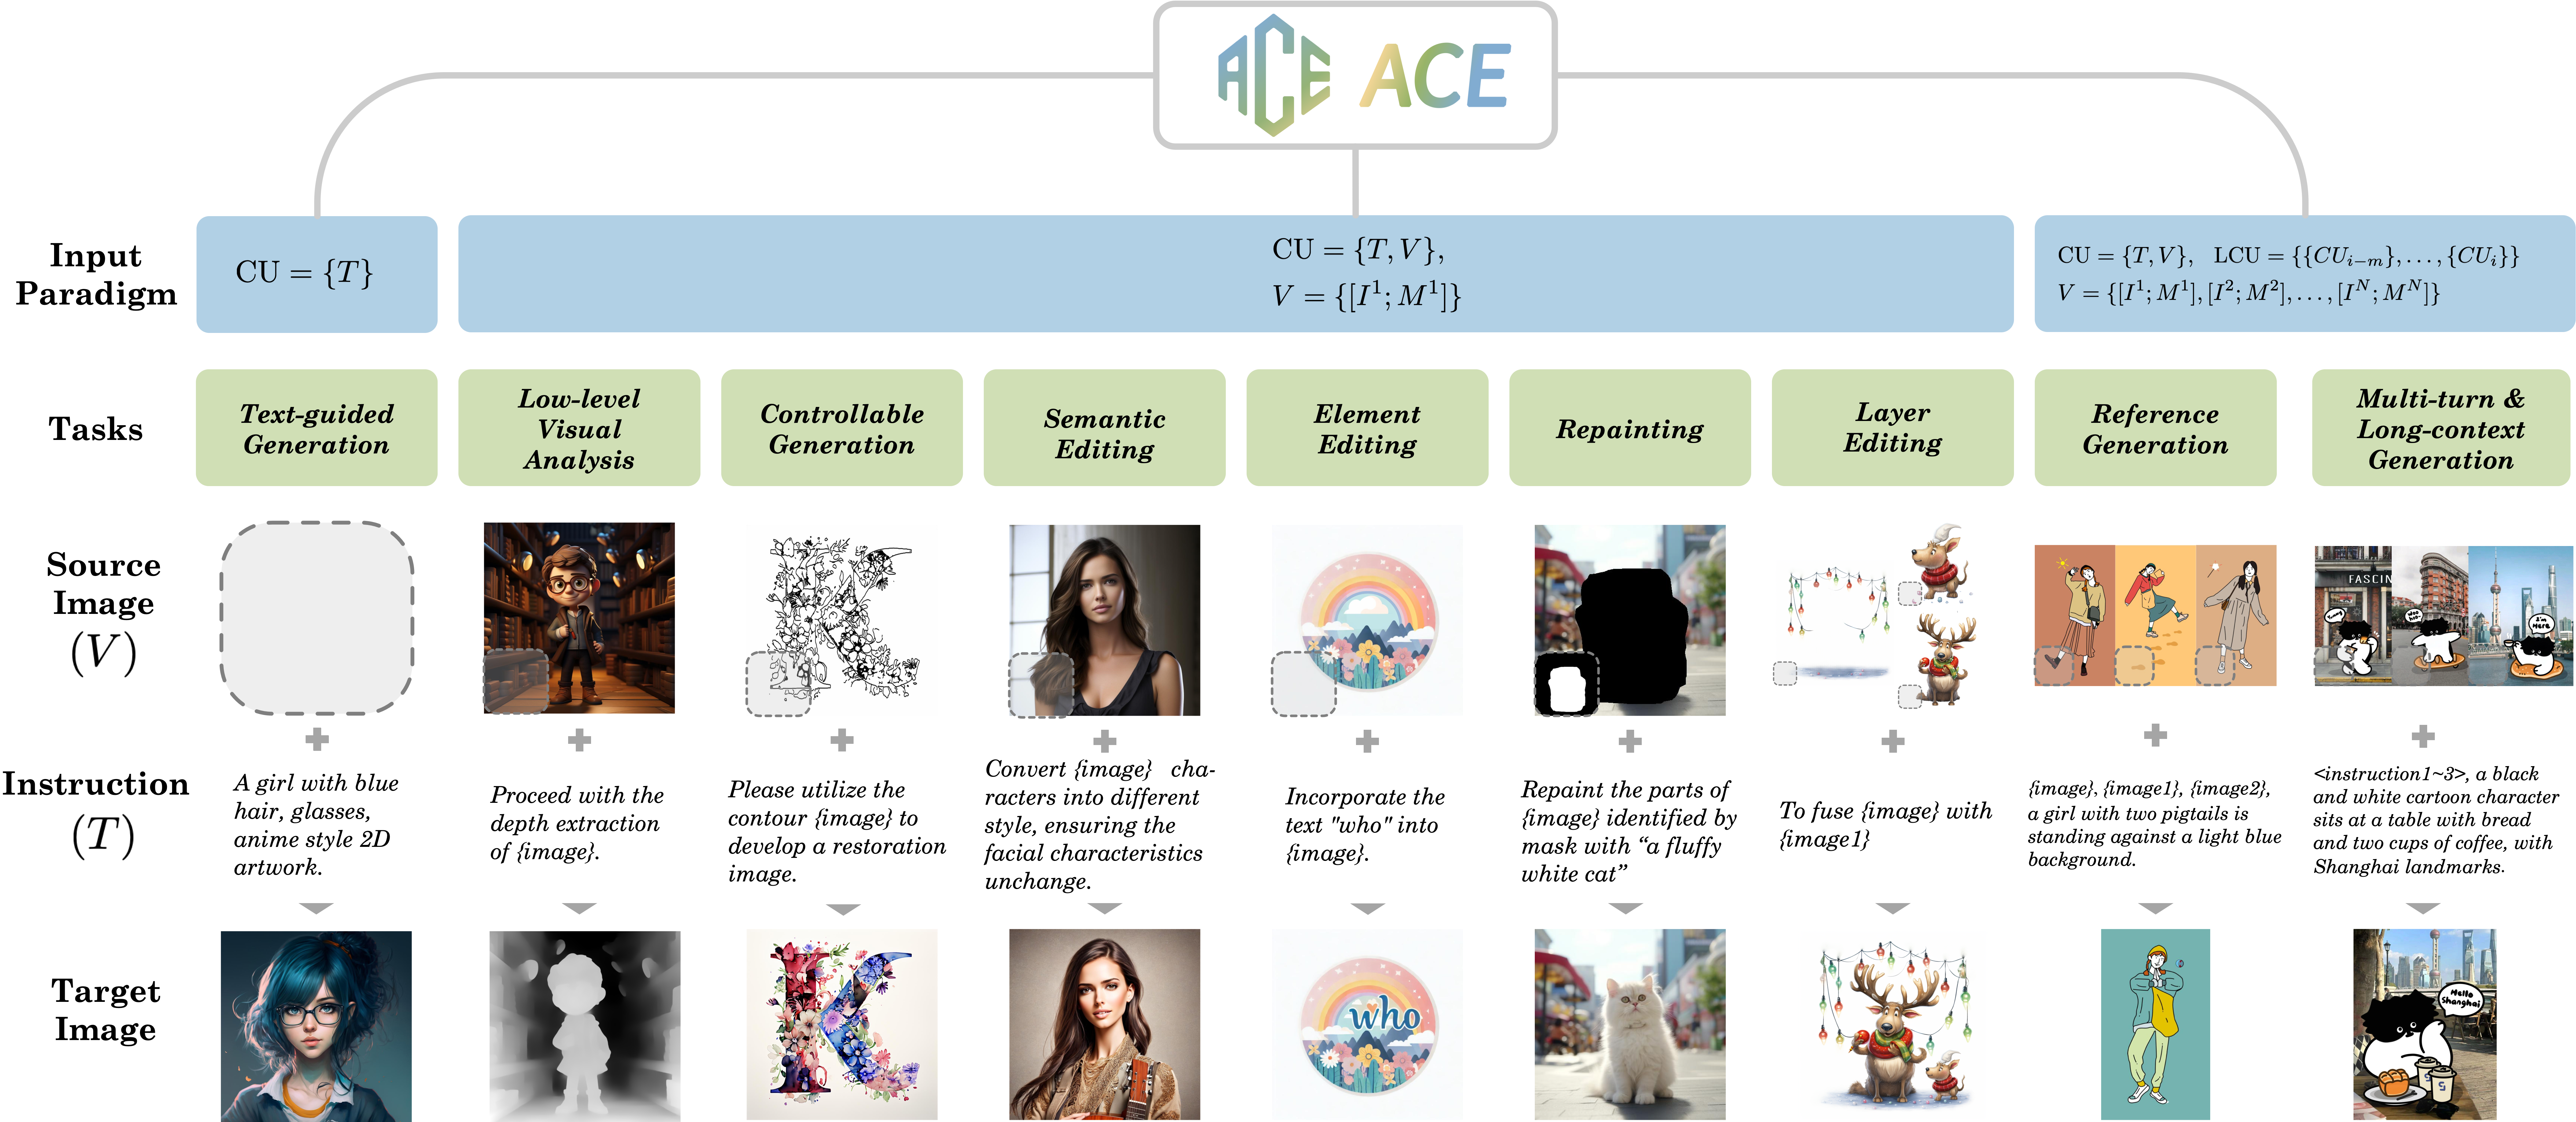](https://ali-vilab.github.io/ace-page/)
|
[//]: # ( <th align="center" colspan="3">Soft Watercolor Style</th>)
|
||||||
|
|
||||||
### ACE Models
|
[//]: # ( </tr>)
|
||||||
| **Model** | **Status** |
|
|
||||||
|:----------------:|:---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------:|
|
|
||||||
| ACE-0.6B-512px | [](https://huggingface.co/spaces/scepter-studio/ACE-Chat)<br>[](https://www.modelscope.cn/models/iic/ACE-0.6B-512px) [](https://huggingface.co/scepter-studio/ACE-0.6B-512px) |
|
|
||||||
| ACE-0.6B-1024px | [](https://huggingface.co/spaces/scepter-studio/ACE-Refiner-Chat)<br>[](https://www.modelscope.cn/models/iic/ACE-0.6B-1024px) [](https://huggingface.co/scepter-studio/ACE-0.6B-1024px) | |
|
|
||||||
| ACE-12B-FLUX-dev | Coming Soon |
|
|
||||||
### ACE Training
|
|
||||||
|
|
||||||
We offer a demonstration training YAML that enables the end-to-end training of ACE using a toy dataset. For a comprehensive overview of the hyperparameter configurations, please consult `scepter/methods/edit/dit_ace_0.6b_512.yaml`.
|
[//]: # ( <tr>)
|
||||||
|
|
||||||
#### Prepare datasets
|
[//]: # ( <td><img src="asset/images/flux_tuner/flux_tuner_2_1.webp" width="200"></td>)
|
||||||
|
|
||||||
Please find the dataset class located in `scepter/modules/data/dataset/ms_dataset.py`,
|
[//]: # ( <td><img src="asset/images/flux_tuner/flux_tuner_2_2.webp" width="200"></td>)
|
||||||
designed to facilitate end-to-end training using an open-source toy dataset.
|
|
||||||
Download a dataset zip file from [modelscope](https://www.modelscope.cn/models/iic/scepter/resolve/master/datasets/hed_pair.zip), and then extract its contents into the `cache/datasets/` directory.
|
|
||||||
|
|
||||||
Should you wish to prepare your own datasets, we recommend consulting `scepter/modules/data/dataset/ms_dataset.py` for detailed guidance on the required data format.
|
[//]: # ( <td><img src="asset/images/flux_tuner/flux_tuner_2_3.webp" width="200"></td>)
|
||||||
|
|
||||||
#### Prepare initial weight
|
[//]: # ( <td><img src="asset/images/flux_tuner/flux_tuner_1_1.webp" width="200"></td>)
|
||||||
The ACE checkpoint has been uploaded to both ModelScope and HuggingFace platforms:
|
|
||||||
* [ModelScope](https://www.modelscope.cn/models/iic/ACE-0.6B-512px)
|
|
||||||
* [HuggingFace](https://huggingface.co/scepter-studio/ACE-0.6B-512px)
|
|
||||||
|
|
||||||
In the provided training YAML configuration, we have designated the Modelscope URL as the default checkpoint URL. Should you wish to transition to Hugging Face, you can effortlessly achieve this by modifying the PRETRAINED_MODEL value within the YAML file (replace the prefix "ms://iic" to "hf://scepter-studio").
|
[//]: # ( <td><img src="asset/images/flux_tuner/flux_tuner_1_2.webp" width="200"></td>)
|
||||||
|
|
||||||
|
[//]: # ( <td><img src="asset/images/flux_tuner/flux_tuner_1_3.webp" width="200"></td>)
|
||||||
|
|
||||||
#### Start training
|
[//]: # ( </tr>)
|
||||||
|
|
||||||
You can easily start training procedure by executing the following command:
|
[//]: # ( <tr>)
|
||||||
```bash
|
|
||||||
# ACE-0.6B-512px
|
|
||||||
PYTHONPATH=. python scepter/tools/run_train.py --cfg scepter/methods/edit/dit_ace_0.6b_512.yaml
|
|
||||||
# ACE-0.6B-1024px
|
|
||||||
PYTHONPATH=. python scepter/tools/run_train.py --cfg scepter/methods/edit/dit_ace_0.6b_1024.yaml
|
|
||||||
```
|
|
||||||
|
|
||||||
### ACE Chat Bot
|
[//]: # ( <th align="center" colspan="3">Travel Style</th>)
|
||||||
|
|
||||||
We have developed a chatbot interface utilizing Gradio, designed to convert user input in natural language into visually captivating images that align semantically with the specified instructions. You can easily access this functionality by launching Scepter Studio with the following command:
|
[//]: # ( <th align="center" colspan="3">WuKong Style</th>)
|
||||||
```bash
|
|
||||||
PYTHONPATH=. python scepter/tools/webui.py --cfg scepter/methods/studio/scepter_ui.yaml --language zh --tab chatbot
|
|
||||||
```
|
|
||||||
Upon starting, you will find a "ChatBot" tab within the Gradio application, which serves as a chat-based interface to handle any requests related to image editing or generation.
|
|
||||||
|
|
||||||
### ACE ComfyUI Workflow
|
[//]: # ( </tr>)
|
||||||
|
|
||||||

|
[//]: # ( <tr>)
|
||||||
|
|
||||||
<table><tbody>
|
[//]: # ( <td><img src="asset/images/flux_tuner/flux_tuner_3_1.webp" width="200"></td>)
|
||||||
<tr>
|
|
||||||
<th align="center" colspan="4">ACE Workflow Examples</th>
|
|
||||||
</tr>
|
|
||||||
<tr>
|
|
||||||
<th align="center" colspan="1">Control</th>
|
|
||||||
<th align="center" colspan="1">Semantic</th>
|
|
||||||
<th align="center" colspan="1">Element</th>
|
|
||||||
</tr>
|
|
||||||
<tr>
|
|
||||||
<td>
|
|
||||||
<a href="https://github.com/ali-vilab/ace-page/raw/main/assets/comfyui/ace_control.png" target="_blank">
|
|
||||||
<img src="https://github.com/ali-vilab/ace-page/raw/main/assets/comfyui/ace_control.png" width="200">
|
|
||||||
</a>
|
|
||||||
</td>
|
|
||||||
<td>
|
|
||||||
<a href="https://github.com/ali-vilab/ace-page/raw/main/assets/comfyui/ace_semantic.png" target="_blank">
|
|
||||||
<img src="https://github.com/ali-vilab/ace-page/raw/main/assets/comfyui/ace_semantic.png" width="200">
|
|
||||||
</a>
|
|
||||||
</td>
|
|
||||||
<td>
|
|
||||||
<a href="https://github.com/ali-vilab/ace-page/raw/main/assets/comfyui/ace_element.png" target="_blank">
|
|
||||||
<img src="https://github.com/ali-vilab/ace-page/raw/main/assets/comfyui/ace_element.png" width="200">
|
|
||||||
</a>
|
|
||||||
</td>
|
|
||||||
</tr>
|
|
||||||
</tbody>
|
|
||||||
</table>
|
|
||||||
|
|
||||||
## 🖼 Gallery for Recent Works
|
[//]: # ( <td><img src="asset/images/flux_tuner/flux_tuner_3_2.webp" width="200"></td>)
|
||||||
|
|
||||||
### FLUX Tuners
|
[//]: # ( <td><img src="asset/images/flux_tuner/flux_tuner_3_3.webp" width="200"></td>)
|
||||||
|
|
||||||
<table><tbody>
|
[//]: # ( <td><img src="asset/images/flux_tuner/flux_tuner_4_1.webp" width="200"></td>)
|
||||||
<tr>
|
|
||||||
<th align="center" colspan="3">Yarn Style</th>
|
[//]: # ( <td><img src="asset/images/flux_tuner/flux_tuner_4_2.webp" width="200"></td>)
|
||||||
<th align="center" colspan="3">Soft Watercolor Style</th>
|
|
||||||
</tr>
|
[//]: # ( <td><img src="asset/images/flux_tuner/flux_tuner_4_3.webp" width="200"></td>)
|
||||||
<tr>
|
|
||||||
<td><img src="asset/images/flux_tuner/flux_tuner_2_1.webp" width="200"></td>
|
[//]: # ( </tr>)
|
||||||
<td><img src="asset/images/flux_tuner/flux_tuner_2_2.webp" width="200"></td>
|
|
||||||
<td><img src="asset/images/flux_tuner/flux_tuner_2_3.webp" width="200"></td>
|
[//]: # (</tbody>)
|
||||||
<td><img src="asset/images/flux_tuner/flux_tuner_1_1.webp" width="200"></td>
|
|
||||||
<td><img src="asset/images/flux_tuner/flux_tuner_1_2.webp" width="200"></td>
|
[//]: # (</table>)
|
||||||
<td><img src="asset/images/flux_tuner/flux_tuner_1_3.webp" width="200"></td>
|
|
||||||
</tr>
|
|
||||||
<tr>
|
|
||||||
<th align="center" colspan="3">Travel Style</th>
|
|
||||||
<th align="center" colspan="3">WuKong Style</th>
|
|
||||||
</tr>
|
|
||||||
<tr>
|
|
||||||
<td><img src="asset/images/flux_tuner/flux_tuner_3_1.webp" width="200"></td>
|
|
||||||
<td><img src="asset/images/flux_tuner/flux_tuner_3_2.webp" width="200"></td>
|
|
||||||
<td><img src="asset/images/flux_tuner/flux_tuner_3_3.webp" width="200"></td>
|
|
||||||
<td><img src="asset/images/flux_tuner/flux_tuner_4_1.webp" width="200"></td>
|
|
||||||
<td><img src="asset/images/flux_tuner/flux_tuner_4_2.webp" width="200"></td>
|
|
||||||
<td><img src="asset/images/flux_tuner/flux_tuner_4_3.webp" width="200"></td>
|
|
||||||
</tr>
|
|
||||||
</tbody>
|
|
||||||
</table>
|
|
||||||
|
|
||||||
### ComfyUI Workflow
|
### ComfyUI Workflow
|
||||||
|
|
||||||
@@ -225,18 +165,19 @@ pip install scepter
|
|||||||
|
|
||||||
### Currently supported approaches
|
### Currently supported approaches
|
||||||
|
|
||||||
| Tasks | Methods | Links |
|
| Tasks | Methods | Links |
|
||||||
|:----------------------------:|:----------------------------------------------:|:------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
|
|:----------------------------:|:------------------------------------------------:|:------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
|
||||||
| Text-to-image Generation | SD v1.5 | [](https://huggingface.co/runwayml/stable-diffusion-v1-5) |
|
| Text-to-image Generation | SD v1.5 | [](https://huggingface.co/runwayml/stable-diffusion-v1-5) |
|
||||||
| Text-to-image Generation | SD v2.1 | [](https://huggingface.co/runwayml/stable-diffusion-v1-5) |
|
| Text-to-image Generation | SD v2.1 | [](https://huggingface.co/runwayml/stable-diffusion-v1-5) |
|
||||||
| Text-to-image Generation | SD-XL | [](https://huggingface.co/stabilityai/stable-diffusion-xl-base-1.0) |
|
| Text-to-image Generation | SD-XL | [](https://huggingface.co/stabilityai/stable-diffusion-xl-base-1.0) |
|
||||||
| Text-to-image Generation | FLUX | [](https://huggingface.co/black-forest-labs/FLUX.1-dev) |
|
| Text-to-image Generation | FLUX | [](https://huggingface.co/black-forest-labs/FLUX.1-dev) |
|
||||||
| Efficient Tuning | LoRA | [](https://arxiv.org/abs/2106.09685) |
|
| Efficient Tuning | LoRA | [](https://arxiv.org/abs/2106.09685) |
|
||||||
| Efficient Tuning | Res-Tuning(NeurIPS23) | [](https://arxiv.org/abs/2310.19859) [](https://res-tuning.github.io/) |
|
| Efficient Tuning | Res-Tuning(NeurIPS23) | [](https://arxiv.org/abs/2310.19859) [](https://res-tuning.github.io/) |
|
||||||
| Controllable Image Synthesis | [🌟SCEdit(CVPR24)](docs/en/tasks/scedit.md) | [](https://arxiv.org/abs/2312.11392) [](https://scedit.github.io/) |
|
| Controllable Image Synthesis | [🌟SCEdit(CVPR24)](docs/en/tasks/scedit.md) | [](https://arxiv.org/abs/2312.11392) [](https://scedit.github.io/) |
|
||||||
| Image Editing | [🌟LAR-Gen](docs/en/tasks/largen.md) | [](https://arxiv.org/abs/2403.19534) [](https://ali-vilab.github.io/largen-page/) |
|
| Image Editing | [🌟LAR-Gen](docs/en/tasks/largen.md) | [](https://arxiv.org/abs/2403.19534) [](https://ali-vilab.github.io/largen-page/) |
|
||||||
| Image Editing | [🌟StyleBooth](docs/en/tasks/stylebooth.md) | [](https://arxiv.org/abs/2404.12154) [](https://ali-vilab.github.io/stylebooth-page/) |
|
| Image Editing | [🌟StyleBooth](docs/en/tasks/stylebooth.md) | [](https://arxiv.org/abs/2404.12154) [](https://ali-vilab.github.io/stylebooth-page/) |
|
||||||
| Image Generation and Editing | [🌟ACE](https://ali-vilab.github.io/ace-page/) | [](https://arxiv.org/abs/2410.00086) [](https://ali-vilab.github.io/ace-page/) [](https://huggingface.co/spaces/scepter-studio/ACE-Chat) <br> [](https://www.modelscope.cn/models/iic/ACE-0.6B-512px) [](https://huggingface.co/scepter-studio/ACE-0.6B-512px) |
|
| Image Generation and Editing | [🌟ACE](https://ali-vilab.github.io/ace-page/) | [](https://arxiv.org/abs/2410.00086) [](https://ali-vilab.github.io/ace-page/) [](https://huggingface.co/spaces/scepter-studio/ACE-Chat) <br> [](https://www.modelscope.cn/models/iic/ACE-0.6B-512px) [](https://huggingface.co/scepter-studio/ACE-0.6B-512px) |
|
||||||
|
| Image Generation and Editing | [🌟ACE++](https://ali-vilab.github.io/ACE_plus_page/) | [](https://arxiv.org/abs/2501.02487) [](https://ali-vilab.github.io/ACE_plus_page/) [](https://huggingface.co/spaces/scepter-studio/ACE-Plus) <br> [](https://www.modelscope.cn/models/iic/ACE_Plus/summary) [](https://huggingface.co/ali-vilab/ACE_Plus/tree/main) |
|
||||||
|
|
||||||
|
|
||||||
## 🖥️ SCEPTER Studio
|
## 🖥️ SCEPTER Studio
|
||||||
|
|||||||
+23
-13
@@ -1,18 +1,28 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
import os
|
from typing import TYPE_CHECKING
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
import scepter
|
|
||||||
from scepter.modules import data, model, opt, solver, transform, utils
|
|
||||||
from scepter.tools.helper import get_module_list as module_list
|
|
||||||
from scepter.tools.helper import \
|
|
||||||
get_module_object_config as configures_by_objects
|
|
||||||
from scepter.tools.helper import get_module_objects as objects_by_module
|
|
||||||
from scepter.version import __version__, version_info
|
|
||||||
|
|
||||||
dirname = os.path.dirname(scepter.__file__)
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules import data, model, opt, solver, transform, utils
|
||||||
|
from scepter.tools.helper import get_module_list as module_list
|
||||||
|
from scepter.tools.helper import \
|
||||||
|
get_module_object_config as configures_by_objects
|
||||||
|
from scepter.tools.helper import get_module_objects as objects_by_module
|
||||||
|
from scepter.version import __version__, version_info
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'modules': ['data', 'model', 'opt', 'solver', 'transform', 'utils'],
|
||||||
|
'helper': ['get_module_list', 'get_module_object_config', 'get_module_objects'],
|
||||||
|
'version': ['__version__', 'version_info']
|
||||||
|
}
|
||||||
|
|
||||||
__all__ = [
|
import sys
|
||||||
utils, transform, data, model, solver, version_info, opt, '__version__',
|
sys.modules[__name__] = LazyImportModule(
|
||||||
'dirname'
|
__name__,
|
||||||
]
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -0,0 +1,277 @@
|
|||||||
|
ENV:
|
||||||
|
BACKEND: nccl
|
||||||
|
SEED: 42
|
||||||
|
TENSOR_PARALLEL_SIZE: 1
|
||||||
|
PIPELINE_PARALLEL_SIZE: 1
|
||||||
|
SYS_ENVS:
|
||||||
|
TORCH_CUDNN_V8_API_ENABLED: '1'
|
||||||
|
TOKENIZERS_PARALLELISM: 'false'
|
||||||
|
TF_CPP_MIN_LOG_LEVEL: '3'
|
||||||
|
PYTORCH_CUDA_ALLOC_CONF: 'expandable_segments:True'
|
||||||
|
#
|
||||||
|
SOLVER:
|
||||||
|
NAME: LatentDiffusionVideoSolver
|
||||||
|
MAX_STEPS: 2000
|
||||||
|
USE_AMP: True
|
||||||
|
DTYPE: bfloat16
|
||||||
|
USE_FAIRSCALE: False
|
||||||
|
USE_FSDP: True
|
||||||
|
LOAD_MODEL_ONLY: False
|
||||||
|
ENABLE_GRADSCALER: False
|
||||||
|
USE_SCALER: False
|
||||||
|
RESUME_FROM:
|
||||||
|
WORK_DIR: ./cache/save_data/dit_cogvideox1.5_5b_i2v_lora
|
||||||
|
LOG_FILE: std_log.txt
|
||||||
|
EVAL_INTERVAL: 100
|
||||||
|
LOG_TRAIN_NUM: 4
|
||||||
|
FPS: 16
|
||||||
|
SHARDING_STRATEGY: full_shard
|
||||||
|
FSDP_REDUCE_DTYPE: float32
|
||||||
|
FSDP_BUFFER_DTYPE: float32
|
||||||
|
FSDP_SHARD_MODULES: [ 'model', 'cond_stage_model.model']
|
||||||
|
SAVE_MODULES: [ 'model', 'cond_stage_model.model']
|
||||||
|
TRAIN_MODULES: ['model']
|
||||||
|
#
|
||||||
|
FILE_SYSTEM:
|
||||||
|
NAME: "ModelscopeFs"
|
||||||
|
TEMP_DIR: "./cache/cache_data"
|
||||||
|
#
|
||||||
|
TUNER:
|
||||||
|
- NAME: SwiftLoRA
|
||||||
|
R: 64
|
||||||
|
LORA_ALPHA: 64
|
||||||
|
LORA_DROPOUT: 0.0
|
||||||
|
BIAS: "none"
|
||||||
|
TARGET_MODULES: "model.*(.to_k|.to_q|.to_v|.to_out.0)$"
|
||||||
|
#
|
||||||
|
MODEL:
|
||||||
|
NAME: LatentDiffusionCogVideoX
|
||||||
|
PRETRAINED_MODEL:
|
||||||
|
PARAMETERIZATION: v
|
||||||
|
TIMESTEPS: 1000
|
||||||
|
MIN_SNR_GAMMA: 3.0
|
||||||
|
ZERO_TERMINAL_SNR: True
|
||||||
|
SCALE_FACTOR_SPATIAL: 8
|
||||||
|
SCALE_FACTOR_TEMPORAL: 4
|
||||||
|
SCALING_FACTOR_IMAGE: 0.7
|
||||||
|
NOISED_IMAGE_DROPOUT: 0.05
|
||||||
|
INVERT_SCALE_LATENTS: True
|
||||||
|
IGNORE_KEYS: [ ]
|
||||||
|
DEFAULT_N_PROMPT:
|
||||||
|
USE_EMA: False
|
||||||
|
EVAL_EMA: False
|
||||||
|
DIFFUSION:
|
||||||
|
NAME: BaseDiffusion
|
||||||
|
PREDICTION_TYPE: v
|
||||||
|
USE_DYNAMIC_CFG: False
|
||||||
|
NOISE_SCHEDULER:
|
||||||
|
NAME: ScaledLinearScheduler
|
||||||
|
BETA_MIN: 0.00085
|
||||||
|
BETA_MAX: 0.012
|
||||||
|
SNR_SHIFT_SCALE: 1.0
|
||||||
|
RESCALE_BETAS_ZERO_SNR: True
|
||||||
|
DIFFUSION_SAMPLERS:
|
||||||
|
NAME: DDIMSampler
|
||||||
|
DISCRETIZATION_TYPE: trailing
|
||||||
|
ETA: 0.0
|
||||||
|
#
|
||||||
|
DIFFUSION_MODEL:
|
||||||
|
NAME: CogVideoXTransformer3DModel
|
||||||
|
DTYPE: bfloat16
|
||||||
|
PRETRAINED_MODEL: # 5b-I2V diff
|
||||||
|
- ms://ZhipuAI/CogVideoX1.5-5B-I2V@transformer/diffusion_pytorch_model-00001-of-00003.safetensors
|
||||||
|
- ms://ZhipuAI/CogVideoX1.5-5B-I2V@transformer/diffusion_pytorch_model-00002-of-00003.safetensors
|
||||||
|
- ms://ZhipuAI/CogVideoX1.5-5B-I2V@transformer/diffusion_pytorch_model-00003-of-00003.safetensors
|
||||||
|
NUM_ATTENTION_HEADS: 48
|
||||||
|
ATTENTION_HEAD_DIM: 64
|
||||||
|
IN_CHANNELS: 32
|
||||||
|
LATENT_CHANNELS: 16
|
||||||
|
OUT_CHANNELS: 16
|
||||||
|
FLIP_SIN_TO_COS: True
|
||||||
|
FREQ_SHIFT: 0
|
||||||
|
TIME_EMBED_DIM: 512
|
||||||
|
TEXT_EMBED_DIM: 4096
|
||||||
|
OFS_EMBED_DIM: 512 # v1.5 diff
|
||||||
|
NUM_LAYERS: 42
|
||||||
|
DROPOUT: 0.0
|
||||||
|
ATTENTION_BIAS: True
|
||||||
|
SAMPLE_WIDTH: 300
|
||||||
|
SAMPLE_HEIGHT: 300
|
||||||
|
SAMPLE_FRAMES: 81
|
||||||
|
PATCH_SIZE: 2
|
||||||
|
PATCH_SIZE_T: 2 # v1.5 diff
|
||||||
|
PATCH_BIAS: False # v1.5 diff
|
||||||
|
TEMPORAL_COMPRESSION_RATIO: 4
|
||||||
|
MAX_TEXT_SEQ_LENGTH: 224
|
||||||
|
ACTIVATION_FN: "gelu-approximate"
|
||||||
|
TIMESTEP_ACTIVATION_FN: "silu"
|
||||||
|
NORM_ELEMENTWISE_AFFINE: True
|
||||||
|
NORM_EPS: 1e-5
|
||||||
|
SPATIAL_INTERPOLATION_SCALE: 1.875
|
||||||
|
TEMPORAL_INTERPOLATION_SCALE: 1.0
|
||||||
|
USE_ROTARY_POSITIONAL_EMBEDDINGS: True
|
||||||
|
USE_LEARNED_POSITIONAL_EMBEDDINGS: False
|
||||||
|
GRADIENT_CHECKPOINTING: True
|
||||||
|
#
|
||||||
|
FIRST_STAGE_MODEL:
|
||||||
|
NAME: AutoencoderKLCogVideoX
|
||||||
|
DTYPE: bfloat16
|
||||||
|
PRETRAINED_MODEL: ms://ZhipuAI/CogVideoX1.5-5B-I2V@vae/diffusion_pytorch_model.safetensors
|
||||||
|
SAMPLE_HEIGHT: 768
|
||||||
|
SAMPLE_WIDTH: 1360
|
||||||
|
USE_QUANT_CONV: False
|
||||||
|
USE_POST_QUANT_CONV: False
|
||||||
|
USE_SLICING: True
|
||||||
|
USE_TILING: True
|
||||||
|
GRADIENT_CHECKPOINTING: True
|
||||||
|
ENCODER:
|
||||||
|
NAME: CogVideoXEncoder3D
|
||||||
|
IN_CHANNELS: 3
|
||||||
|
OUT_CHANNELS: 16
|
||||||
|
UP_BLOCK_TYPES: [ "CogVideoXDownBlock3D", "CogVideoXDownBlock3D", "CogVideoXDownBlock3D", "CogVideoXDownBlock3D" ]
|
||||||
|
BLOCK_OUT_CHANNELS: [ 128, 256, 256, 512 ]
|
||||||
|
LAYERS_PER_BLOCK: 3
|
||||||
|
ACT_FN: "silu"
|
||||||
|
NORM_EPS: 1e-6
|
||||||
|
NORM_NUM_GROUPS: 32
|
||||||
|
DROPOUT: 0.0
|
||||||
|
PAD_MODE: "first"
|
||||||
|
TEMPORAL_COMPRESSION_RATIO: 4
|
||||||
|
GRADIENT_CHECKPOINTING: True
|
||||||
|
DECODER:
|
||||||
|
NAME: CogVideoXDecoder3D
|
||||||
|
IN_CHANNELS: 16
|
||||||
|
OUT_CHANNELS: 3
|
||||||
|
UP_BLOCK_TYPES: [ "CogVideoXUpBlock3D", "CogVideoXUpBlock3D", "CogVideoXUpBlock3D", "CogVideoXUpBlock3D" ]
|
||||||
|
BLOCK_OUT_CHANNELS: [ 128, 256, 256, 512 ]
|
||||||
|
LAYERS_PER_BLOCK: 3
|
||||||
|
ACT_FN: "silu"
|
||||||
|
NORM_EPS: 1e-6
|
||||||
|
NORM_NUM_GROUPS: 32
|
||||||
|
DROPOUT: 0.0
|
||||||
|
PAD_MODE: "first"
|
||||||
|
TEMPORAL_COMPRESSION_RATIO: 4
|
||||||
|
GRADIENT_CHECKPOINTING: True
|
||||||
|
#
|
||||||
|
COND_STAGE_MODEL:
|
||||||
|
NAME: T5EmbedderHF
|
||||||
|
PRETRAINED_MODEL: ms://AI-ModelScope/t5-v1_1-xxl
|
||||||
|
TOKENIZER_PATH: ms://AI-ModelScope/t5-v1_1-xxl
|
||||||
|
LENGTH: 224
|
||||||
|
CLEAN:
|
||||||
|
USE_GRAD: False
|
||||||
|
T5_DTYPE: bfloat16
|
||||||
|
#
|
||||||
|
LOSS:
|
||||||
|
NAME: ReconstructLoss
|
||||||
|
LOSS_TYPE: l2
|
||||||
|
#
|
||||||
|
SAMPLE_ARGS:
|
||||||
|
SAMPLER: ddim
|
||||||
|
SAMPLE_STEPS: 50
|
||||||
|
SEED: 42
|
||||||
|
GUIDE_SCALE: 6.0
|
||||||
|
GUIDE_RESCALE: 0.0
|
||||||
|
NUM_FRAMES: 81
|
||||||
|
IMAGE_SIZE: [768, 1360]
|
||||||
|
#
|
||||||
|
OPTIMIZER:
|
||||||
|
NAME: Adam
|
||||||
|
LEARNING_RATE: 1e-3
|
||||||
|
BETAS: [ 0.9, 0.95 ]
|
||||||
|
EPS: 1e-8
|
||||||
|
WEIGHT_DECAY: 0.0
|
||||||
|
AMSGRAD: False
|
||||||
|
#
|
||||||
|
# LR_SCHEDULER:
|
||||||
|
# NAME: StepAnnealingLR
|
||||||
|
# WARMUP_STEPS: 200
|
||||||
|
# TOTAL_STEPS: 2000
|
||||||
|
# DECAY_MODE: 'cosine'
|
||||||
|
#
|
||||||
|
TRAIN_DATA:
|
||||||
|
NAME: VideoGenDataset
|
||||||
|
MODE: train
|
||||||
|
PIN_MEMORY: True
|
||||||
|
BATCH_SIZE: 1
|
||||||
|
NUM_WORKERS: 0
|
||||||
|
NUM_FRAMES: 85
|
||||||
|
FPS: 16
|
||||||
|
HEIGHT: 768
|
||||||
|
WIDTH: 1360
|
||||||
|
PROMPT_PREFIX: 'DISNEY '
|
||||||
|
DATA_TYPE: 'i2v'
|
||||||
|
SAMPLER:
|
||||||
|
NAME: MixtureOfSamplers
|
||||||
|
SUB_SAMPLERS:
|
||||||
|
- NAME: MultiLevelBatchSampler
|
||||||
|
PROB: 1.0
|
||||||
|
FIELDS: [ "video_path", "prompt" ]
|
||||||
|
DELIMITER: '#;#'
|
||||||
|
PATH_PREFIX: cache/datasets/Disney-VideoGeneration-Dataset/
|
||||||
|
INDEX_FILE: cache/datasets/Disney-VideoGeneration-Dataset/index.jsonl
|
||||||
|
TRANSFORMS:
|
||||||
|
- NAME: Select
|
||||||
|
KEYS: [ "video", "image", "prompt" ]
|
||||||
|
META_KEYS: [ ]
|
||||||
|
#
|
||||||
|
# EVAL_DATA:
|
||||||
|
# NAME: Text2ImageDataset
|
||||||
|
# MODE: eval
|
||||||
|
# PROMPT_FILE:
|
||||||
|
# PROMPT_DATA: [ "A cat running.#;#asset/images/edit_tuner/cat_512.jpg" ]
|
||||||
|
# FIELDS: [ "prompt", "img_path" ]
|
||||||
|
# DELIMITER: '#;#'
|
||||||
|
# PROMPT_PREFIX: ''
|
||||||
|
# PIN_MEMORY: True
|
||||||
|
# BATCH_SIZE: 1
|
||||||
|
# USE_NUM: 8
|
||||||
|
# NUM_WORKERS: 0
|
||||||
|
# IMAGE_SIZE: [768, 1360]
|
||||||
|
# TRANSFORMS:
|
||||||
|
# - NAME: LoadImageFromFileList
|
||||||
|
# FILE_KEYS: [ 'img_path' ]
|
||||||
|
# RGB_ORDER: RGB
|
||||||
|
# BACKEND: pillow
|
||||||
|
# - NAME: FlexibleResize
|
||||||
|
# INTERPOLATION: bilinear
|
||||||
|
# SIZE: [768, 1360]
|
||||||
|
# INPUT_KEY: [ 'img' ]
|
||||||
|
# OUTPUT_KEY: [ 'img' ]
|
||||||
|
# BACKEND: pillow
|
||||||
|
# - NAME: FlexibleCenterCrop
|
||||||
|
# SIZE: [768, 1360]
|
||||||
|
# INPUT_KEY: [ 'img' ]
|
||||||
|
# OUTPUT_KEY: [ 'img' ]
|
||||||
|
# BACKEND: pillow
|
||||||
|
# - NAME: ImageToTensor
|
||||||
|
# INPUT_KEY: [ 'img' ]
|
||||||
|
# OUTPUT_KEY: [ 'img' ]
|
||||||
|
# BACKEND: pillow
|
||||||
|
# - NAME: Normalize
|
||||||
|
# MEAN: [ 0.5, 0.5, 0.5 ]
|
||||||
|
# STD: [ 0.5, 0.5, 0.5 ]
|
||||||
|
# INPUT_KEY: [ 'img' ]
|
||||||
|
# OUTPUT_KEY: [ 'image' ]
|
||||||
|
# BACKEND: torchvision
|
||||||
|
# - NAME: Select
|
||||||
|
# KEYS: [ 'image', 'prompt' ]
|
||||||
|
# META_KEYS: [ 'image_size' ]
|
||||||
|
#
|
||||||
|
TRAIN_HOOKS:
|
||||||
|
- NAME: ProbeDataHook
|
||||||
|
PROB_INTERVAL: 100
|
||||||
|
PRIORITY: 0
|
||||||
|
- NAME: BackwardHook
|
||||||
|
PRIORITY: 10
|
||||||
|
- NAME: LogHook
|
||||||
|
LOG_INTERVAL: 10
|
||||||
|
PRIORITY: 20
|
||||||
|
- NAME: CheckpointHook
|
||||||
|
INTERVAL: 1000
|
||||||
|
PRIORITY: 40
|
||||||
|
#
|
||||||
|
# EVAL_HOOKS:
|
||||||
|
# - NAME: ProbeDataHook
|
||||||
|
# PROB_INTERVAL: 100
|
||||||
|
# PRIORITY: 0
|
||||||
@@ -0,0 +1,248 @@
|
|||||||
|
ENV:
|
||||||
|
BACKEND: nccl
|
||||||
|
SEED: 42
|
||||||
|
TENSOR_PARALLEL_SIZE: 1
|
||||||
|
PIPELINE_PARALLEL_SIZE: 1
|
||||||
|
SYS_ENVS:
|
||||||
|
TORCH_CUDNN_V8_API_ENABLED: '1'
|
||||||
|
TOKENIZERS_PARALLELISM: 'false'
|
||||||
|
TF_CPP_MIN_LOG_LEVEL: '3'
|
||||||
|
PYTORCH_CUDA_ALLOC_CONF: 'expandable_segments:True'
|
||||||
|
#
|
||||||
|
SOLVER:
|
||||||
|
NAME: LatentDiffusionVideoSolver
|
||||||
|
MAX_STEPS: 2000
|
||||||
|
USE_AMP: True
|
||||||
|
DTYPE: bfloat16
|
||||||
|
USE_FAIRSCALE: False
|
||||||
|
USE_FSDP: True
|
||||||
|
LOAD_MODEL_ONLY: False
|
||||||
|
ENABLE_GRADSCALER: False
|
||||||
|
USE_SCALER: False
|
||||||
|
RESUME_FROM:
|
||||||
|
WORK_DIR: ./cache/save_data/dit_cogvideox1.5_5b_lora
|
||||||
|
LOG_FILE: std_log.txt
|
||||||
|
EVAL_INTERVAL: 100
|
||||||
|
LOG_TRAIN_NUM: 4
|
||||||
|
FPS: 16
|
||||||
|
SHARDING_STRATEGY: full_shard
|
||||||
|
FSDP_REDUCE_DTYPE: float32
|
||||||
|
FSDP_BUFFER_DTYPE: float32
|
||||||
|
FSDP_SHARD_MODULES: [ 'model', 'cond_stage_model.model']
|
||||||
|
SAVE_MODULES: [ 'model', 'cond_stage_model.model']
|
||||||
|
TRAIN_MODULES: ['model']
|
||||||
|
#
|
||||||
|
FILE_SYSTEM:
|
||||||
|
NAME: "ModelscopeFs"
|
||||||
|
TEMP_DIR: "./cache/cache_data"
|
||||||
|
#
|
||||||
|
TUNER:
|
||||||
|
- NAME: SwiftLoRA
|
||||||
|
R: 64
|
||||||
|
LORA_ALPHA: 64
|
||||||
|
LORA_DROPOUT: 0.0
|
||||||
|
BIAS: "none"
|
||||||
|
TARGET_MODULES: "model.*(.to_k|.to_q|.to_v|.to_out.0)$"
|
||||||
|
#
|
||||||
|
MODEL:
|
||||||
|
NAME: LatentDiffusionCogVideoX
|
||||||
|
PRETRAINED_MODEL:
|
||||||
|
PARAMETERIZATION: v
|
||||||
|
TIMESTEPS: 1000
|
||||||
|
MIN_SNR_GAMMA: 3.0
|
||||||
|
ZERO_TERMINAL_SNR: True
|
||||||
|
SCALE_FACTOR_SPATIAL: 8
|
||||||
|
SCALE_FACTOR_TEMPORAL: 4
|
||||||
|
SCALING_FACTOR_IMAGE: 0.7
|
||||||
|
INVERT_SCALE_LATENTS: True
|
||||||
|
IGNORE_KEYS: [ ]
|
||||||
|
DEFAULT_N_PROMPT:
|
||||||
|
USE_EMA: False
|
||||||
|
EVAL_EMA: False
|
||||||
|
DIFFUSION:
|
||||||
|
NAME: BaseDiffusion
|
||||||
|
PREDICTION_TYPE: v
|
||||||
|
USE_DYNAMIC_CFG: False
|
||||||
|
NOISE_SCHEDULER:
|
||||||
|
NAME: ScaledLinearScheduler
|
||||||
|
BETA_MIN: 0.00085
|
||||||
|
BETA_MAX: 0.012
|
||||||
|
SNR_SHIFT_SCALE: 1.0
|
||||||
|
RESCALE_BETAS_ZERO_SNR: True
|
||||||
|
DIFFUSION_SAMPLERS:
|
||||||
|
NAME: DDIMSampler
|
||||||
|
DISCRETIZATION_TYPE: trailing
|
||||||
|
ETA: 0.0
|
||||||
|
#
|
||||||
|
DIFFUSION_MODEL:
|
||||||
|
NAME: CogVideoXTransformer3DModel
|
||||||
|
DTYPE: bfloat16
|
||||||
|
PRETRAINED_MODEL:
|
||||||
|
- ms://ZhipuAI/CogVideoX1.5-5B@transformer/diffusion_pytorch_model-00001-of-00003.safetensors
|
||||||
|
- ms://ZhipuAI/CogVideoX1.5-5B@transformer/diffusion_pytorch_model-00002-of-00003.safetensors
|
||||||
|
- ms://ZhipuAI/CogVideoX1.5-5B@transformer/diffusion_pytorch_model-00003-of-00003.safetensors
|
||||||
|
NUM_ATTENTION_HEADS: 48
|
||||||
|
ATTENTION_HEAD_DIM: 64
|
||||||
|
IN_CHANNELS: 16
|
||||||
|
OUT_CHANNELS: 16
|
||||||
|
FLIP_SIN_TO_COS: True
|
||||||
|
FREQ_SHIFT: 0
|
||||||
|
TIME_EMBED_DIM: 512
|
||||||
|
TEXT_EMBED_DIM: 4096
|
||||||
|
NUM_LAYERS: 42
|
||||||
|
DROPOUT: 0.0
|
||||||
|
ATTENTION_BIAS: True
|
||||||
|
SAMPLE_WIDTH: 300
|
||||||
|
SAMPLE_HEIGHT: 300
|
||||||
|
SAMPLE_FRAMES: 81
|
||||||
|
PATCH_SIZE: 2
|
||||||
|
PATCH_SIZE_T: 2 # v1.5 diff
|
||||||
|
PATCH_BIAS: False # v1.5 diff
|
||||||
|
TEMPORAL_COMPRESSION_RATIO: 4
|
||||||
|
MAX_TEXT_SEQ_LENGTH: 224
|
||||||
|
ACTIVATION_FN: "gelu-approximate"
|
||||||
|
TIMESTEP_ACTIVATION_FN: "silu"
|
||||||
|
NORM_ELEMENTWISE_AFFINE: True
|
||||||
|
NORM_EPS: 1e-5
|
||||||
|
SPATIAL_INTERPOLATION_SCALE: 1.875
|
||||||
|
TEMPORAL_INTERPOLATION_SCALE: 1.0
|
||||||
|
USE_ROTARY_POSITIONAL_EMBEDDINGS: True
|
||||||
|
USE_LEARNED_POSITIONAL_EMBEDDINGS: False
|
||||||
|
GRADIENT_CHECKPOINTING: True
|
||||||
|
#
|
||||||
|
FIRST_STAGE_MODEL:
|
||||||
|
NAME: AutoencoderKLCogVideoX
|
||||||
|
DTYPE: bfloat16
|
||||||
|
PRETRAINED_MODEL: ms://ZhipuAI/CogVideoX1.5-5B@vae/diffusion_pytorch_model.safetensors
|
||||||
|
SAMPLE_HEIGHT: 768
|
||||||
|
SAMPLE_WIDTH: 1360
|
||||||
|
USE_QUANT_CONV: False
|
||||||
|
USE_POST_QUANT_CONV: False
|
||||||
|
USE_SLICING: True
|
||||||
|
USE_TILING: True
|
||||||
|
GRADIENT_CHECKPOINTING: True
|
||||||
|
ENCODER:
|
||||||
|
NAME: CogVideoXEncoder3D
|
||||||
|
IN_CHANNELS: 3
|
||||||
|
OUT_CHANNELS: 16
|
||||||
|
UP_BLOCK_TYPES: [ "CogVideoXDownBlock3D", "CogVideoXDownBlock3D", "CogVideoXDownBlock3D", "CogVideoXDownBlock3D" ]
|
||||||
|
BLOCK_OUT_CHANNELS: [ 128, 256, 256, 512 ]
|
||||||
|
LAYERS_PER_BLOCK: 3
|
||||||
|
ACT_FN: "silu"
|
||||||
|
NORM_EPS: 1e-6
|
||||||
|
NORM_NUM_GROUPS: 32
|
||||||
|
DROPOUT: 0.0
|
||||||
|
PAD_MODE: "first"
|
||||||
|
TEMPORAL_COMPRESSION_RATIO: 4
|
||||||
|
GRADIENT_CHECKPOINTING: True
|
||||||
|
DECODER:
|
||||||
|
NAME: CogVideoXDecoder3D
|
||||||
|
IN_CHANNELS: 16
|
||||||
|
OUT_CHANNELS: 3
|
||||||
|
UP_BLOCK_TYPES: [ "CogVideoXUpBlock3D", "CogVideoXUpBlock3D", "CogVideoXUpBlock3D", "CogVideoXUpBlock3D" ]
|
||||||
|
BLOCK_OUT_CHANNELS: [ 128, 256, 256, 512 ]
|
||||||
|
LAYERS_PER_BLOCK: 3
|
||||||
|
ACT_FN: "silu"
|
||||||
|
NORM_EPS: 1e-6
|
||||||
|
NORM_NUM_GROUPS: 32
|
||||||
|
DROPOUT: 0.0
|
||||||
|
PAD_MODE: "first"
|
||||||
|
TEMPORAL_COMPRESSION_RATIO: 4
|
||||||
|
GRADIENT_CHECKPOINTING: True
|
||||||
|
#
|
||||||
|
COND_STAGE_MODEL:
|
||||||
|
NAME: T5EmbedderHF
|
||||||
|
PRETRAINED_MODEL: ms://AI-ModelScope/t5-v1_1-xxl
|
||||||
|
TOKENIZER_PATH: ms://AI-ModelScope/t5-v1_1-xxl
|
||||||
|
LENGTH: 224
|
||||||
|
CLEAN:
|
||||||
|
USE_GRAD: False
|
||||||
|
T5_DTYPE: bfloat16
|
||||||
|
#
|
||||||
|
LOSS:
|
||||||
|
NAME: ReconstructLoss
|
||||||
|
LOSS_TYPE: l2
|
||||||
|
#
|
||||||
|
SAMPLE_ARGS:
|
||||||
|
SAMPLER: ddim
|
||||||
|
SAMPLE_STEPS: 50
|
||||||
|
SEED: 42
|
||||||
|
GUIDE_SCALE: 6.0
|
||||||
|
GUIDE_RESCALE: 0.0
|
||||||
|
NUM_FRAMES: 81
|
||||||
|
IMAGE_SIZE: [768, 1360]
|
||||||
|
#
|
||||||
|
OPTIMIZER:
|
||||||
|
NAME: Adam
|
||||||
|
LEARNING_RATE: 1e-3
|
||||||
|
BETAS: [ 0.9, 0.95 ]
|
||||||
|
EPS: 1e-8
|
||||||
|
WEIGHT_DECAY: 0.0
|
||||||
|
AMSGRAD: False
|
||||||
|
#
|
||||||
|
# LR_SCHEDULER:
|
||||||
|
# NAME: StepAnnealingLR
|
||||||
|
# WARMUP_STEPS: 200
|
||||||
|
# TOTAL_STEPS: 2000
|
||||||
|
# DECAY_MODE: 'cosine'
|
||||||
|
#
|
||||||
|
TRAIN_DATA:
|
||||||
|
NAME: VideoGenDataset
|
||||||
|
MODE: train
|
||||||
|
PIN_MEMORY: True
|
||||||
|
BATCH_SIZE: 1
|
||||||
|
NUM_WORKERS: 0
|
||||||
|
NUM_FRAMES: 85
|
||||||
|
FPS: 16
|
||||||
|
HEIGHT: 768
|
||||||
|
WIDTH: 1360
|
||||||
|
PROMPT_PREFIX: 'DISNEY '
|
||||||
|
SAMPLER:
|
||||||
|
NAME: MixtureOfSamplers
|
||||||
|
SUB_SAMPLERS:
|
||||||
|
- NAME: MultiLevelBatchSampler
|
||||||
|
PROB: 1.0
|
||||||
|
FIELDS: [ "video_path", "prompt" ]
|
||||||
|
DELIMITER: '#;#'
|
||||||
|
PATH_PREFIX: cache/datasets/Disney-VideoGeneration-Dataset/
|
||||||
|
INDEX_FILE: cache/datasets/Disney-VideoGeneration-Dataset/index.jsonl
|
||||||
|
TRANSFORMS:
|
||||||
|
- NAME: Select
|
||||||
|
KEYS: [ 'video', "prompt" ]
|
||||||
|
META_KEYS: [ ]
|
||||||
|
#
|
||||||
|
EVAL_DATA:
|
||||||
|
NAME: Text2ImageDataset
|
||||||
|
MODE: eval
|
||||||
|
PROMPT_FILE:
|
||||||
|
PROMPT_DATA: [ "A girl riding a bike." ]
|
||||||
|
IMAGE_SIZE: [ 768, 1360 ]
|
||||||
|
FIELDS: [ "prompt" ]
|
||||||
|
DELIMITER: '#;#'
|
||||||
|
PROMPT_PREFIX: 'DISNEY ' # ''
|
||||||
|
PIN_MEMORY: True
|
||||||
|
BATCH_SIZE: 1
|
||||||
|
USE_NUM: 8
|
||||||
|
NUM_WORKERS: 0
|
||||||
|
TRANSFORMS:
|
||||||
|
- NAME: Select
|
||||||
|
KEYS: [ 'index', 'prompt' ]
|
||||||
|
META_KEYS: [ 'image_size' ]
|
||||||
|
#
|
||||||
|
TRAIN_HOOKS:
|
||||||
|
- NAME: ProbeDataHook
|
||||||
|
PROB_INTERVAL: 100
|
||||||
|
PRIORITY: 0
|
||||||
|
- NAME: BackwardHook
|
||||||
|
PRIORITY: 10
|
||||||
|
- NAME: LogHook
|
||||||
|
LOG_INTERVAL: 10
|
||||||
|
PRIORITY: 20
|
||||||
|
- NAME: CheckpointHook
|
||||||
|
INTERVAL: 1000
|
||||||
|
PRIORITY: 40
|
||||||
|
#
|
||||||
|
EVAL_HOOKS:
|
||||||
|
- NAME: ProbeDataHook
|
||||||
|
PROB_INTERVAL: 100
|
||||||
|
PRIORITY: 0
|
||||||
@@ -183,6 +183,10 @@ SOLVER:
|
|||||||
PIN_MEMORY: True
|
PIN_MEMORY: True
|
||||||
BATCH_SIZE: 1
|
BATCH_SIZE: 1
|
||||||
NUM_WORKERS: 4
|
NUM_WORKERS: 4
|
||||||
|
NUM_FRAMES: 49
|
||||||
|
FPS: 8
|
||||||
|
HEIGHT: 480
|
||||||
|
WIDTH: 720
|
||||||
PROMPT_PREFIX: 'DISNEY '
|
PROMPT_PREFIX: 'DISNEY '
|
||||||
SAMPLER:
|
SAMPLER:
|
||||||
NAME: MixtureOfSamplers
|
NAME: MixtureOfSamplers
|
||||||
|
|||||||
@@ -188,6 +188,10 @@ SOLVER:
|
|||||||
PIN_MEMORY: True
|
PIN_MEMORY: True
|
||||||
BATCH_SIZE: 1
|
BATCH_SIZE: 1
|
||||||
NUM_WORKERS: 0
|
NUM_WORKERS: 0
|
||||||
|
NUM_FRAMES: 49
|
||||||
|
FPS: 8
|
||||||
|
HEIGHT: 480
|
||||||
|
WIDTH: 720
|
||||||
PROMPT_PREFIX: 'DISNEY '
|
PROMPT_PREFIX: 'DISNEY '
|
||||||
DATA_TYPE: 'i2v'
|
DATA_TYPE: 'i2v'
|
||||||
SAMPLER:
|
SAMPLER:
|
||||||
|
|||||||
@@ -185,6 +185,10 @@ SOLVER:
|
|||||||
PIN_MEMORY: True
|
PIN_MEMORY: True
|
||||||
BATCH_SIZE: 1
|
BATCH_SIZE: 1
|
||||||
NUM_WORKERS: 4
|
NUM_WORKERS: 4
|
||||||
|
NUM_FRAMES: 49
|
||||||
|
FPS: 8
|
||||||
|
HEIGHT: 480
|
||||||
|
WIDTH: 720
|
||||||
PROMPT_PREFIX: 'DISNEY '
|
PROMPT_PREFIX: 'DISNEY '
|
||||||
DELIMITER: '#;#'
|
DELIMITER: '#;#'
|
||||||
FIELDS: [ 'video_path', 'prompt' ]
|
FIELDS: [ 'video_path', 'prompt' ]
|
||||||
|
|||||||
@@ -148,4 +148,5 @@ MODEL:
|
|||||||
TOKENIZER_PATH: ms://AI-ModelScope/t5-v1_1-xxl
|
TOKENIZER_PATH: ms://AI-ModelScope/t5-v1_1-xxl
|
||||||
LENGTH: 226
|
LENGTH: 226
|
||||||
CLEAN:
|
CLEAN:
|
||||||
USE_GRAD: False
|
USE_GRAD: False
|
||||||
|
T5_DTYPE: bfloat16
|
||||||
@@ -150,4 +150,5 @@ MODEL:
|
|||||||
TOKENIZER_PATH: ms://AI-ModelScope/t5-v1_1-xxl
|
TOKENIZER_PATH: ms://AI-ModelScope/t5-v1_1-xxl
|
||||||
LENGTH: 226
|
LENGTH: 226
|
||||||
CLEAN:
|
CLEAN:
|
||||||
USE_GRAD: False
|
USE_GRAD: False
|
||||||
|
T5_DTYPE: bfloat16
|
||||||
@@ -1,4 +1,5 @@
|
|||||||
WORK_DIR: "inference"
|
WORK_DIR: "inference"
|
||||||
|
SKIP_EXAMPLES: True
|
||||||
DIFFUSION_PARAS:
|
DIFFUSION_PARAS:
|
||||||
SAMPLE:
|
SAMPLE:
|
||||||
VALUES: ['ddim', 'euler', 'euler_ancestral', 'heun', 'dpm2',
|
VALUES: ['ddim', 'euler', 'euler_ancestral', 'heun', 'dpm2',
|
||||||
|
|||||||
@@ -1,4 +1,23 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules import (data, inference, model, opt, solver, transform,
|
from typing import TYPE_CHECKING
|
||||||
utils)
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules import (data, inference, model, opt, solver, transform,
|
||||||
|
utils)
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'modules': ['data', 'inference', 'model', 'opt', 'solver',
|
||||||
|
'transform', 'utils']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -1,23 +1,60 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.annotator.base_annotator import GeneralAnnotator
|
from typing import TYPE_CHECKING
|
||||||
from scepter.modules.annotator.canny import CannyAnnotator
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
from scepter.modules.annotator.color import ColorAnnotator
|
|
||||||
from scepter.modules.annotator.degradation import DegradationAnnotator
|
if TYPE_CHECKING:
|
||||||
from scepter.modules.annotator.doodle import DoodleAnnotator
|
from scepter.modules.annotator.base_annotator import GeneralAnnotator
|
||||||
from scepter.modules.annotator.gray import GrayAnnotator
|
from scepter.modules.annotator.canny import CannyAnnotator
|
||||||
from scepter.modules.annotator.hed import HedAnnotator
|
from scepter.modules.annotator.color import ColorAnnotator
|
||||||
from scepter.modules.annotator.identity import IdentityAnnotator
|
from scepter.modules.annotator.degradation import DegradationAnnotator
|
||||||
from scepter.modules.annotator.informative_drawing import (
|
from scepter.modules.annotator.doodle import DoodleAnnotator
|
||||||
InfoDrawAnimeAnnotator, InfoDrawContourAnnotator,
|
from scepter.modules.annotator.gray import GrayAnnotator
|
||||||
InfoDrawOpenSketchAnnotator)
|
from scepter.modules.annotator.hed import HedAnnotator
|
||||||
from scepter.modules.annotator.inpainting import InpaintingAnnotator
|
from scepter.modules.annotator.identity import IdentityAnnotator
|
||||||
from scepter.modules.annotator.invert import InvertAnnotator
|
from scepter.modules.annotator.informative_drawing import (
|
||||||
from scepter.modules.annotator.midas_op import MidasDetector
|
InfoDrawAnimeAnnotator, InfoDrawContourAnnotator,
|
||||||
from scepter.modules.annotator.mlsd_op import MLSDdetector
|
InfoDrawOpenSketchAnnotator)
|
||||||
from scepter.modules.annotator.openpose import OpenposeAnnotator
|
from scepter.modules.annotator.inpainting import InpaintingAnnotator
|
||||||
from scepter.modules.annotator.outpainting import OutpaintingAnnotator, OutpaintingResize
|
from scepter.modules.annotator.invert import InvertAnnotator
|
||||||
from scepter.modules.annotator.pidinet import PiDiAnnotator
|
from scepter.modules.annotator.midas_op import MidasDetector
|
||||||
from scepter.modules.annotator.segmentation import ESAMAnnotator
|
from scepter.modules.annotator.mlsd_op import MLSDdetector
|
||||||
from scepter.modules.annotator.sketch import SketchAnnotator
|
from scepter.modules.annotator.openpose import OpenposeAnnotator
|
||||||
from scepter.modules.annotator.lama import LamaAnnotator
|
from scepter.modules.annotator.outpainting import OutpaintingAnnotator, OutpaintingResize
|
||||||
|
from scepter.modules.annotator.pidinet import PiDiAnnotator
|
||||||
|
from scepter.modules.annotator.segmentation import ESAMAnnotator
|
||||||
|
from scepter.modules.annotator.sketch import SketchAnnotator
|
||||||
|
from scepter.modules.annotator.lama import LamaAnnotator
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'base_annotator': ['GeneralAnnotator'],
|
||||||
|
'canny': ['CannyAnnotator'],
|
||||||
|
'color': ['ColorAnnotator'],
|
||||||
|
'degradation': ['DegradationAnnotator'],
|
||||||
|
'doodle': ['DoodleAnnotator'],
|
||||||
|
'gray': ['GrayAnnotator'],
|
||||||
|
'hed': ['HedAnnotator'],
|
||||||
|
'identity': ['IdentityAnnotator'],
|
||||||
|
'informative_drawing': ['InfoDrawAnimeAnnotator',
|
||||||
|
'InfoDrawContourAnnotator',
|
||||||
|
'InfoDrawOpenSketchAnnotator'],
|
||||||
|
'inpainting': ['InpaintingAnnotator'],
|
||||||
|
'invert': ['InvertAnnotator'],
|
||||||
|
'midas_op': ['MidasDetector'],
|
||||||
|
'mlsd_op': ['MLSDdetector'],
|
||||||
|
'openpose': ['OpenposeAnnotator'],
|
||||||
|
'outpainting': ['OutpaintingAnnotator', 'OutpaintingResize'],
|
||||||
|
'pidinet': ['PiDiAnnotator'],
|
||||||
|
'segmentation': ['ESAMAnnotator'],
|
||||||
|
'sketch': ['SketchAnnotator'],
|
||||||
|
'lama': ['LamaAnnotator'],
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -114,7 +114,7 @@ class HedAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
|||||||
pretrained_model = cfg.get('PRETRAINED_MODEL', None)
|
pretrained_model = cfg.get('PRETRAINED_MODEL', None)
|
||||||
if pretrained_model:
|
if pretrained_model:
|
||||||
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
||||||
self.netNetwork.load_state_dict(torch.load(local_path))
|
self.netNetwork.load_state_dict(torch.load(local_path, weights_only=True))
|
||||||
|
|
||||||
@torch.no_grad()
|
@torch.no_grad()
|
||||||
@torch.inference_mode()
|
@torch.inference_mode()
|
||||||
|
|||||||
@@ -120,7 +120,7 @@ class InfoDrawContourAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
|||||||
self.model = ContourInference(input_nc, output_nc, n_residual_blocks,
|
self.model = ContourInference(input_nc, output_nc, n_residual_blocks,
|
||||||
sigmoid)
|
sigmoid)
|
||||||
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
||||||
self.model.load_state_dict(torch.load(local_path))
|
self.model.load_state_dict(torch.load(local_path, weights_only=True))
|
||||||
self.model = self.model.eval().requires_grad_(False).to(we.device_id)
|
self.model = self.model.eval().requires_grad_(False).to(we.device_id)
|
||||||
|
|
||||||
@torch.no_grad()
|
@torch.no_grad()
|
||||||
|
|||||||
@@ -10,7 +10,7 @@ class BaseModel(torch.nn.Module):
|
|||||||
Args:
|
Args:
|
||||||
path (str): file path
|
path (str): file path
|
||||||
"""
|
"""
|
||||||
parameters = torch.load(path, map_location=torch.device('cpu'))
|
parameters = torch.load(path, map_location=torch.device('cpu'), weights_only=True)
|
||||||
|
|
||||||
if 'optimizer' in parameters:
|
if 'optimizer' in parameters:
|
||||||
parameters = parameters['model']
|
parameters = parameters['model']
|
||||||
|
|||||||
@@ -29,7 +29,7 @@ class MLSDdetector(BaseAnnotator, metaclass=ABCMeta):
|
|||||||
pretrained_model = cfg.get('PRETRAINED_MODEL', None)
|
pretrained_model = cfg.get('PRETRAINED_MODEL', None)
|
||||||
if pretrained_model:
|
if pretrained_model:
|
||||||
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
||||||
model.load_state_dict(torch.load(local_path), strict=True)
|
model.load_state_dict(torch.load(local_path, weights_only=True), strict=True)
|
||||||
self.model = model.eval()
|
self.model = model.eval()
|
||||||
self.thr_v = cfg.get('THR_V', 0.1)
|
self.thr_v = cfg.get('THR_V', 0.1)
|
||||||
self.thr_d = cfg.get('THR_D', 0.1)
|
self.thr_d = cfg.get('THR_D', 0.1)
|
||||||
|
|||||||
@@ -423,7 +423,7 @@ class Hand(object):
|
|||||||
self.model = handpose_model()
|
self.model = handpose_model()
|
||||||
if torch.cuda.is_available():
|
if torch.cuda.is_available():
|
||||||
self.model = self.model.to(device)
|
self.model = self.model.to(device)
|
||||||
model_dict = transfer(self.model, torch.load(model_path))
|
model_dict = transfer(self.model, torch.load(model_path, weights_only=True))
|
||||||
self.model.load_state_dict(model_dict)
|
self.model.load_state_dict(model_dict)
|
||||||
self.model.eval()
|
self.model.eval()
|
||||||
self.device = device
|
self.device = device
|
||||||
@@ -503,7 +503,7 @@ class Body(object):
|
|||||||
self.model = bodypose_model()
|
self.model = bodypose_model()
|
||||||
if torch.cuda.is_available():
|
if torch.cuda.is_available():
|
||||||
self.model = self.model.to(device)
|
self.model = self.model.to(device)
|
||||||
model_dict = transfer(self.model, torch.load(model_path))
|
model_dict = transfer(self.model, torch.load(model_path, weights_only=True))
|
||||||
self.model.load_state_dict(model_dict)
|
self.model.load_state_dict(model_dict)
|
||||||
self.model.eval()
|
self.model.eval()
|
||||||
self.device = device
|
self.device = device
|
||||||
|
|||||||
@@ -882,7 +882,7 @@ class PiDiAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
|||||||
if pretrained_model:
|
if pretrained_model:
|
||||||
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
||||||
state = torch.load(local_path,
|
state = torch.load(local_path,
|
||||||
map_location='cpu')['state_dict']
|
map_location='cpu', weights_only=True)['state_dict']
|
||||||
if vanilla_cnn:
|
if vanilla_cnn:
|
||||||
state = convert_pidinet(state, 'carv4')
|
state = convert_pidinet(state, 'carv4')
|
||||||
state = {
|
state = {
|
||||||
|
|||||||
@@ -10,7 +10,11 @@ import torchvision.transforms as T
|
|||||||
from PIL import Image
|
from PIL import Image
|
||||||
from pycocotools import mask as mask_utils
|
from pycocotools import mask as mask_utils
|
||||||
from scipy import ndimage
|
from scipy import ndimage
|
||||||
from sklearn.cluster import KMeans
|
try:
|
||||||
|
from sklearn.cluster import KMeans
|
||||||
|
except:
|
||||||
|
import warnings
|
||||||
|
warnings.warn("ignore sklearn import, please pip install scikit-learn.")
|
||||||
from torchvision.ops.boxes import batched_nms
|
from torchvision.ops.boxes import batched_nms
|
||||||
|
|
||||||
from scepter.modules.annotator.base_annotator import BaseAnnotator
|
from scepter.modules.annotator.base_annotator import BaseAnnotator
|
||||||
|
|||||||
@@ -86,7 +86,7 @@ class SketchAnnotator(BaseAnnotator, metaclass=ABCMeta):
|
|||||||
std=0.0858381272736797).eval()
|
std=0.0858381272736797).eval()
|
||||||
if pretrained_model:
|
if pretrained_model:
|
||||||
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
||||||
state = torch.load(local_path, map_location='cpu')
|
state = torch.load(local_path, map_location='cpu', weights_only=True)
|
||||||
self.model.load_state_dict(state)
|
self.model.load_state_dict(state)
|
||||||
|
|
||||||
@torch.no_grad()
|
@torch.no_grad()
|
||||||
|
|||||||
@@ -1,4 +1,21 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
from typing import TYPE_CHECKING
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
from scepter.modules.data import dataset, sampler
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.data import dataset, sampler
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'data': ['dataset', 'sampler']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -1,12 +1,35 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
from typing import TYPE_CHECKING
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
from scepter.modules.data.dataset.base_dataset import BaseDataset
|
|
||||||
from scepter.modules.data.dataset.dataset import (Image2ImageDataset,
|
if TYPE_CHECKING:
|
||||||
ImageClassifyPublicDataset,
|
from scepter.modules.data.dataset.base_dataset import BaseDataset
|
||||||
ImageTextPairDataset,
|
from scepter.modules.data.dataset.dataset import (Image2ImageDataset,
|
||||||
Text2ImageDataset)
|
ImageClassifyPublicDataset,
|
||||||
from scepter.modules.data.dataset.ms_dataset import (
|
ImageTextPairDataset,
|
||||||
ImageTextPairFolderDataset, ImageTextPairMSDataset)
|
Text2ImageDataset)
|
||||||
from scepter.modules.data.dataset.registry import DATASETS
|
from scepter.modules.data.dataset.ms_dataset import (
|
||||||
from scepter.modules.data.dataset.video_gen_dataset import VideoGenDataset
|
ImageTextPairFolderDataset, ImageTextPairMSDataset)
|
||||||
|
from scepter.modules.data.dataset.registry import DATASETS
|
||||||
|
from scepter.modules.data.dataset.video_gen_dataset import VideoGenDataset
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'base_dataset': ['BaseDataset'],
|
||||||
|
'dataset': ['Image2ImageDataset', 'ImageClassifyPublicDataset',
|
||||||
|
'ImageTextPairDataset', 'Text2ImageDataset'],
|
||||||
|
'ms_dataset': ['ImageTextPairFolderDataset',
|
||||||
|
'ImageTextPairMSDataset'],
|
||||||
|
'registry': ['DATASETS'],
|
||||||
|
'video_gen_dataset': ['VideoGenDataset']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -82,7 +82,7 @@ class BaseDataset(Dataset, metaclass=ABCMeta):
|
|||||||
overwrite=False)
|
overwrite=False)
|
||||||
self.worker_id = worker_id
|
self.worker_id = worker_id
|
||||||
self.logger = self.worker_logger
|
self.logger = self.worker_logger
|
||||||
self.local_we["seed"] += (worker_id + we.rank)
|
self.local_we["seed"] += (worker_id + self.local_we['rank'] * 1234)
|
||||||
self.seed = self.local_we["seed"]
|
self.seed = self.local_we["seed"]
|
||||||
we.set_env(self.local_we)
|
we.set_env(self.local_we)
|
||||||
|
|
||||||
|
|||||||
@@ -4,6 +4,7 @@
|
|||||||
import numbers
|
import numbers
|
||||||
import os
|
import os
|
||||||
import sys
|
import sys
|
||||||
|
import copy
|
||||||
from collections.abc import Iterable
|
from collections.abc import Iterable
|
||||||
|
|
||||||
import numpy as np
|
import numpy as np
|
||||||
|
|||||||
@@ -386,6 +386,11 @@ class ImageTextPairMSDatasetForACE(BaseDataset):
|
|||||||
'description':
|
'description':
|
||||||
'The keywords sign you want to add, which is like <{HIGHLIGHT_KEYWORDS}{KEYWORDS_SIGN}>'
|
'The keywords sign you want to add, which is like <{HIGHLIGHT_KEYWORDS}{KEYWORDS_SIGN}>'
|
||||||
},
|
},
|
||||||
|
'ALIGN_SIZE': {
|
||||||
|
'value': False,
|
||||||
|
'description':
|
||||||
|
'Whether ensure the size align between the source image and target image.'
|
||||||
|
},
|
||||||
'OUTPUT_SIZE': {
|
'OUTPUT_SIZE': {
|
||||||
'value':
|
'value':
|
||||||
None,
|
None,
|
||||||
@@ -414,6 +419,8 @@ class ImageTextPairMSDatasetForACE(BaseDataset):
|
|||||||
self.replace_keywords = cfg.get('HIGHLIGHT_KEYWORDS', '')
|
self.replace_keywords = cfg.get('HIGHLIGHT_KEYWORDS', '')
|
||||||
self.keywords_sign = cfg.get('KEYWORDS_SIGN', '')
|
self.keywords_sign = cfg.get('KEYWORDS_SIGN', '')
|
||||||
self.add_indicator = cfg.get('ADD_INDICATOR', False)
|
self.add_indicator = cfg.get('ADD_INDICATOR', False)
|
||||||
|
|
||||||
|
self.align_size = cfg.get('ALIGN_SIZE', False)
|
||||||
# Use modelscope dataset
|
# Use modelscope dataset
|
||||||
if not ms_dataset_name:
|
if not ms_dataset_name:
|
||||||
raise ValueError(
|
raise ValueError(
|
||||||
@@ -492,7 +499,7 @@ class ImageTextPairMSDatasetForACE(BaseDataset):
|
|||||||
tar_image_path,
|
tar_image_path,
|
||||||
cvt_type='RGB')
|
cvt_type='RGB')
|
||||||
src_image = self.image_preprocess(src_image)
|
src_image = self.image_preprocess(src_image)
|
||||||
tar_image = self.image_preprocess(tar_image)
|
tar_image = self.image_preprocess(tar_image, size = src_image.shape[:2] if self.align_size else None)
|
||||||
|
|
||||||
tar_image = self.transforms(tar_image)
|
tar_image = self.transforms(tar_image)
|
||||||
src_image = self.transforms(src_image)
|
src_image = self.transforms(src_image)
|
||||||
@@ -501,13 +508,13 @@ class ImageTextPairMSDatasetForACE(BaseDataset):
|
|||||||
if self.add_indicator:
|
if self.add_indicator:
|
||||||
if '{image}' not in prompt:
|
if '{image}' not in prompt:
|
||||||
prompt = '{image}, ' + prompt
|
prompt = '{image}, ' + prompt
|
||||||
|
|
||||||
return {
|
return {
|
||||||
'edit_image': [src_image],
|
'src_image_list': [src_image],
|
||||||
'edit_image_mask': [src_mask],
|
'src_mask_list': [src_mask],
|
||||||
'image': tar_image,
|
'image': tar_image,
|
||||||
'image_mask': tar_mask,
|
'image_mask': tar_mask,
|
||||||
'prompt': [prompt],
|
'prompt': [prompt],
|
||||||
|
'edit_id': [0]
|
||||||
}
|
}
|
||||||
|
|
||||||
def load_image(self, prefix, img_path, cvt_type=None):
|
def load_image(self, prefix, img_path, cvt_type=None):
|
||||||
|
|||||||
@@ -337,8 +337,12 @@ def build_dataset_config(cfg, registry, logger=None, *args, **kwargs):
|
|||||||
f'registry must be type Registry, got {type(registry)}')
|
f'registry must be type Registry, got {type(registry)}')
|
||||||
|
|
||||||
cfg = deep_copy(cfg)
|
cfg = deep_copy(cfg)
|
||||||
|
|
||||||
req_type = cfg.get('NAME')
|
req_type = cfg.get('NAME')
|
||||||
|
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
sig = (registry.name.upper(), req_type)
|
||||||
|
LazyImportModule.import_module(sig)
|
||||||
|
|
||||||
if isinstance(req_type, str):
|
if isinstance(req_type, str):
|
||||||
req_type_entry = registry.get(req_type)
|
req_type_entry = registry.get(req_type)
|
||||||
if req_type_entry is None:
|
if req_type_entry is None:
|
||||||
|
|||||||
@@ -1,44 +1,46 @@
|
|||||||
|
# -*- coding: utf-8 -*-
|
||||||
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
import io
|
import io
|
||||||
|
import os
|
||||||
import random
|
import random
|
||||||
import sys
|
import sys
|
||||||
import os
|
|
||||||
import warnings
|
import warnings
|
||||||
|
|
||||||
import torch
|
|
||||||
import numpy as np
|
import numpy as np
|
||||||
|
import torch
|
||||||
from tqdm import tqdm
|
from tqdm import tqdm
|
||||||
|
|
||||||
from scepter.modules.utils.distribute import we
|
|
||||||
from scepter.modules.data.dataset import DATASETS, BaseDataset
|
from scepter.modules.data.dataset import DATASETS, BaseDataset
|
||||||
|
from scepter.modules.utils.distribute import we
|
||||||
from scepter.modules.utils.file_system import FS
|
from scepter.modules.utils.file_system import FS
|
||||||
|
|
||||||
try:
|
try:
|
||||||
import decord
|
import decord
|
||||||
decord.bridge.set_bridge("torch")
|
decord.bridge.set_bridge('torch')
|
||||||
except ImportError:
|
except ImportError:
|
||||||
warnings.warn(
|
warnings.warn(
|
||||||
"The `decord` package is required for loading the video dataset. Install with `pip install decord`"
|
'The `decord` package is required for loading the video dataset. Install with `pip install decord`'
|
||||||
)
|
)
|
||||||
|
|
||||||
|
|
||||||
@DATASETS.register_class()
|
@DATASETS.register_class()
|
||||||
class VideoGenDataset(BaseDataset):
|
class VideoGenDataset(BaseDataset):
|
||||||
def __init__(self, cfg, logger = None):
|
def __init__(self, cfg, logger=None):
|
||||||
super().__init__(cfg, logger=logger)
|
super().__init__(cfg, logger=logger)
|
||||||
self.prompt_prefix = cfg.get('PROMPT_PREFIX', '')
|
self.prompt_prefix = cfg.get('PROMPT_PREFIX', '')
|
||||||
self.path_prefix = cfg.get('PATH_PREFIX', '')
|
self.path_prefix = cfg.get('PATH_PREFIX', '')
|
||||||
self.p_zero = cfg.get('P_ZERO', 0.0)
|
self.p_zero = cfg.get('P_ZERO', 0.0)
|
||||||
self.max_num_frames = cfg.get("NUM_FRAMES", 49)
|
self.max_num_frames = cfg.get('NUM_FRAMES', 49)
|
||||||
self.fps = cfg.get("FPS", 8)
|
self.fps = cfg.get('FPS', 8)
|
||||||
self.height = cfg.get("HEIGHT", 480)
|
self.height = cfg.get('HEIGHT', 480)
|
||||||
self.width = cfg.get("WIDTH", 720)
|
self.width = cfg.get('WIDTH', 720)
|
||||||
self.skip_frames_start = cfg.get("SKIP_FRAMES_START", 0)
|
self.skip_frames_start = cfg.get('SKIP_FRAMES_START', 0)
|
||||||
self.skip_frames_end = cfg.get("SKIP_FRAMES_END", 0)
|
self.skip_frames_end = cfg.get('SKIP_FRAMES_END', 0)
|
||||||
self.data_type = cfg.get('DATA_TYPE', 't2v')
|
self.data_type = cfg.get('DATA_TYPE', 't2v')
|
||||||
|
|
||||||
def worker_init_fn(self, worker_id, num_workers=1):
|
def worker_init_fn(self, worker_id, num_workers=1):
|
||||||
super().worker_init_fn(worker_id, num_workers=num_workers)
|
super().worker_init_fn(worker_id, num_workers=num_workers)
|
||||||
randseed = np.random.randint(0, 2 ** 32 - num_workers - 1)
|
randseed = np.random.randint(0, 2**32 - num_workers - 1)
|
||||||
workerseed = randseed + worker_id
|
workerseed = randseed + worker_id
|
||||||
random.seed(workerseed)
|
random.seed(workerseed)
|
||||||
np.random.seed(workerseed)
|
np.random.seed(workerseed)
|
||||||
@@ -46,7 +48,9 @@ class VideoGenDataset(BaseDataset):
|
|||||||
def _preprocess_video_data(self, video_path):
|
def _preprocess_video_data(self, video_path):
|
||||||
|
|
||||||
with FS.get_object(video_path) as video_data:
|
with FS.get_object(video_path) as video_data:
|
||||||
video_reader = decord.VideoReader(io.BytesIO(video_data), width=self.width, height=self.height)
|
video_reader = decord.VideoReader(io.BytesIO(video_data),
|
||||||
|
width=self.width,
|
||||||
|
height=self.height)
|
||||||
video_num_frames = len(video_reader)
|
video_num_frames = len(video_reader)
|
||||||
|
|
||||||
start_frame = min(self.skip_frames_start, video_num_frames)
|
start_frame = min(self.skip_frames_start, video_num_frames)
|
||||||
@@ -54,13 +58,16 @@ class VideoGenDataset(BaseDataset):
|
|||||||
if end_frame <= start_frame:
|
if end_frame <= start_frame:
|
||||||
frames = video_reader.get_batch([start_frame])
|
frames = video_reader.get_batch([start_frame])
|
||||||
elif end_frame - start_frame <= self.max_num_frames:
|
elif end_frame - start_frame <= self.max_num_frames:
|
||||||
frames = video_reader.get_batch(list(range(start_frame, end_frame)))
|
frames = video_reader.get_batch(list(range(start_frame,
|
||||||
|
end_frame)))
|
||||||
else:
|
else:
|
||||||
indices = list(range(start_frame, end_frame, (end_frame - start_frame) // self.max_num_frames))
|
indices = list(
|
||||||
|
range(start_frame, end_frame,
|
||||||
|
(end_frame - start_frame) // self.max_num_frames))
|
||||||
frames = video_reader.get_batch(indices)
|
frames = video_reader.get_batch(indices)
|
||||||
|
|
||||||
# Ensure that we don't go over the limit
|
# Ensure that we don't go over the limit
|
||||||
frames = frames[: self.max_num_frames]
|
frames = frames[:self.max_num_frames]
|
||||||
selected_num_frames = frames.shape[0]
|
selected_num_frames = frames.shape[0]
|
||||||
|
|
||||||
# Choose first (4k + 1) frames as this is how many is required by the VAE
|
# Choose first (4k + 1) frames as this is how many is required by the VAE
|
||||||
@@ -73,14 +80,16 @@ class VideoGenDataset(BaseDataset):
|
|||||||
|
|
||||||
# Training transforms
|
# Training transforms
|
||||||
frames = frames.float().div_(127.5).sub_(1.)
|
frames = frames.float().div_(127.5).sub_(1.)
|
||||||
frames = frames.permute(3, 0, 1, 2).contiguous() # [C, F, H, W]
|
frames = frames.permute(3, 0, 1, 2).contiguous() # [C, F, H, W]
|
||||||
return frames
|
return frames
|
||||||
|
|
||||||
def _parse_index(self, index):
|
def _parse_index(self, index):
|
||||||
meta = dict()
|
meta = dict()
|
||||||
for key, value in zip(index[-1], index[:-1]):
|
for key, value in zip(index[-1], index[:-1]):
|
||||||
if key in ['oss_key', 'path', 'video_path']:
|
if key in ['oss_key', 'path', 'video_path', 'target_video_path']:
|
||||||
meta['video_path'] = value
|
meta['video_path'] = value
|
||||||
|
elif key in ['source_video_path', 'src_video_path']:
|
||||||
|
meta['src_video_path'] = value
|
||||||
elif key in ['prompt', 'caption', 'text']:
|
elif key in ['prompt', 'caption', 'text']:
|
||||||
meta['prompt'] = value
|
meta['prompt'] = value
|
||||||
elif key in ['width', 'height']:
|
elif key in ['width', 'height']:
|
||||||
@@ -104,8 +113,13 @@ class VideoGenDataset(BaseDataset):
|
|||||||
'prompt': prompt,
|
'prompt': prompt,
|
||||||
'meta': meta,
|
'meta': meta,
|
||||||
}
|
}
|
||||||
if self.data_type == 'i2v':
|
if 'i2v' in self.data_type:
|
||||||
item['image'] = item['video'][:, :1, :, :]
|
item['image'] = item['video'][:, :1, :, :]
|
||||||
|
if 'v2v' in self.data_type:
|
||||||
|
src_video_path = os.path.join(self.path_prefix,
|
||||||
|
meta.get('src_video_path', ''))
|
||||||
|
src_video = self._preprocess_video_data(src_video_path)
|
||||||
|
item['src_video'] = src_video
|
||||||
return item
|
return item
|
||||||
|
|
||||||
def __len__(self):
|
def __len__(self):
|
||||||
@@ -122,7 +136,6 @@ class VideoGenDataset(BaseDataset):
|
|||||||
return collect
|
return collect
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
@DATASETS.register_class()
|
@DATASETS.register_class()
|
||||||
class VideoGenDatasetOTF(VideoGenDataset):
|
class VideoGenDatasetOTF(VideoGenDataset):
|
||||||
def __init__(self, cfg, logger=None):
|
def __init__(self, cfg, logger=None):
|
||||||
@@ -135,8 +148,11 @@ class VideoGenDatasetOTF(VideoGenDataset):
|
|||||||
from scepter.modules.model.registry import MODELS
|
from scepter.modules.model.registry import MODELS
|
||||||
model_cfg = cfg.get('MODEL', None)
|
model_cfg = cfg.get('MODEL', None)
|
||||||
if model_cfg is not None:
|
if model_cfg is not None:
|
||||||
self.model = MODELS.build(cfg.MODEL, logger=logger).eval().requires_grad_(False).to(we.device_id)
|
self.model = MODELS.build(
|
||||||
self.items = self.parse_data(self.data_file, self.delimiter, self.fields)
|
cfg.MODEL,
|
||||||
|
logger=logger).eval().requires_grad_(False).to(we.device_id)
|
||||||
|
self.items = self.parse_data(self.data_file, self.delimiter,
|
||||||
|
self.fields)
|
||||||
if self.use_num and self.use_num > 0:
|
if self.use_num and self.use_num > 0:
|
||||||
self.items = self.items[:self.use_num]
|
self.items = self.items[:self.use_num]
|
||||||
self.data = self.encode(self.items)
|
self.data = self.encode(self.items)
|
||||||
@@ -169,11 +185,13 @@ class VideoGenDatasetOTF(VideoGenDataset):
|
|||||||
return items
|
return items
|
||||||
|
|
||||||
def encode(self, items):
|
def encode(self, items):
|
||||||
self.logger.info("Start to encode video data [{}]!".format(len(items)))
|
self.logger.info('Start to encode video data [{}]!'.format(len(items)))
|
||||||
for item in tqdm(items):
|
for item in tqdm(items):
|
||||||
video_path = os.path.join(self.path_prefix, item.get('video_path', ''))
|
video_path = os.path.join(self.path_prefix,
|
||||||
|
item.get('video_path', ''))
|
||||||
video = self._preprocess_video_data(video_path)
|
video = self._preprocess_video_data(video_path)
|
||||||
latent = self.model.encode_first_stage(video.unsqueeze(0).to(we.device_id)).squeeze(0)
|
latent = self.model.encode_first_stage(
|
||||||
|
video.unsqueeze(0).to(we.device_id)).squeeze(0)
|
||||||
item['video_latent'] = latent.detach().cpu()
|
item['video_latent'] = latent.detach().cpu()
|
||||||
item['video'] = video
|
item['video'] = video
|
||||||
if self.data_type == 'i2v':
|
if self.data_type == 'i2v':
|
||||||
@@ -181,4 +199,4 @@ class VideoGenDatasetOTF(VideoGenDataset):
|
|||||||
return items
|
return items
|
||||||
|
|
||||||
def _get(self, index):
|
def _get(self, index):
|
||||||
return self.data[index % self.real_number]
|
return self.data[index % self.real_number]
|
||||||
|
|||||||
@@ -1,9 +1,31 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
from typing import TYPE_CHECKING
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
from scepter.modules.data.sampler.base_sampler import BaseSampler
|
|
||||||
from scepter.modules.data.sampler.registry import SAMPLERS
|
if TYPE_CHECKING:
|
||||||
from scepter.modules.data.sampler.sampler import (
|
from scepter.modules.data.sampler.base_sampler import BaseSampler
|
||||||
EvalDistributedSampler, LoopSampler, MixtureOfSamplers,
|
from scepter.modules.data.sampler.registry import SAMPLERS
|
||||||
MultiFoldDistributedSampler, MultiLevelBatchSampler,
|
from scepter.modules.data.sampler.sampler import (
|
||||||
MultiLevelBatchSamplerMultiSource, ResolutionBatchSampler)
|
EvalDistributedSampler, LoopSampler, MixtureOfSamplers,
|
||||||
|
MultiFoldDistributedSampler, MultiLevelBatchSampler,
|
||||||
|
MultiLevelBatchSamplerMultiSource, ResolutionBatchSampler)
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'base_sampler': ['BaseSampler'],
|
||||||
|
'registry': ['SAMPLERS'],
|
||||||
|
'sampler': ['EvalDistributedSampler', 'LoopSampler',
|
||||||
|
'MixtureOfSamplers', 'MultiFoldDistributedSampler',
|
||||||
|
'MultiLevelBatchSampler', 'MultiLevelBatchSamplerMultiSource',
|
||||||
|
'ResolutionBatchSampler']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -35,8 +35,12 @@ def build_sampler_config(cfg, registry, logger=None, **kwargs):
|
|||||||
f'registry must be type Registry, got {type(registry)}')
|
f'registry must be type Registry, got {type(registry)}')
|
||||||
|
|
||||||
cfg = deep_copy(cfg)
|
cfg = deep_copy(cfg)
|
||||||
|
|
||||||
req_type = cfg.get('NAME')
|
req_type = cfg.get('NAME')
|
||||||
|
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
sig = (registry.name.upper(), req_type)
|
||||||
|
LazyImportModule.import_module(sig)
|
||||||
|
|
||||||
if isinstance(req_type, str):
|
if isinstance(req_type, str):
|
||||||
req_type_entry = registry.get(req_type)
|
req_type_entry = registry.get(req_type)
|
||||||
if req_type_entry is None:
|
if req_type_entry is None:
|
||||||
|
|||||||
@@ -1,4 +1,21 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
from typing import TYPE_CHECKING
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
from scepter.modules.data.utils.data_bucket import BucketManager
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.data.utils.data_bucket import BucketManager
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'data_bucket': ['BucketManager']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -1,3 +1,39 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.inference.diffusion_inference import DiffusionInference
|
from typing import TYPE_CHECKING
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.inference.diffusion_inference import DiffusionInference
|
||||||
|
from scepter.modules.inference.ace_inference import ACEInference
|
||||||
|
from scepter.modules.inference.cogvideox_inference import CogVideoXInference
|
||||||
|
from scepter.modules.inference.control_inference import ControlInference
|
||||||
|
from scepter.modules.inference.flux_inference import FluxInference
|
||||||
|
from scepter.modules.inference.largen_inference import LargenInference
|
||||||
|
from scepter.modules.inference.pixart_inference import PixArtInference
|
||||||
|
from scepter.modules.inference.sd3_inference import SD3Inference
|
||||||
|
from scepter.modules.inference.stylebooth_inference import StyleboothInference
|
||||||
|
from scepter.modules.inference.tuner_inference import TunerInference
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'diffusion_inference': ['DiffusionInference'],
|
||||||
|
'ace_inference': ['ACEInference'],
|
||||||
|
'cogvideox_inference': ['CogVideoXInference'],
|
||||||
|
'control_inference': ['ControlInference'],
|
||||||
|
'flux_inference': ['FluxInference'],
|
||||||
|
'largen_inference': ['LargenInference'],
|
||||||
|
'pixart_inference': ['PixArtInference'],
|
||||||
|
'sd3_inference': ['SD3Inference'],
|
||||||
|
'stylebooth_inference': ['StyleboothInference'],
|
||||||
|
'tuner_inference': ['TunerInference']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -11,7 +11,6 @@ import torch
|
|||||||
from scepter.modules.utils.file_system import FS
|
from scepter.modules.utils.file_system import FS
|
||||||
from scepter.modules.utils.distribute import we
|
from scepter.modules.utils.distribute import we
|
||||||
from scepter.modules.model.backbone.cogvideox.utils import get_3d_rotary_pos_embed, get_resize_crop_region_for_grid
|
from scepter.modules.model.backbone.cogvideox.utils import get_3d_rotary_pos_embed, get_resize_crop_region_for_grid
|
||||||
|
|
||||||
from .diffusion_inference import DiffusionInference, get_model
|
from .diffusion_inference import DiffusionInference, get_model
|
||||||
from .tuner_inference import TunerInference
|
from .tuner_inference import TunerInference
|
||||||
|
|
||||||
@@ -27,9 +26,13 @@ class CogVideoXInference(DiffusionInference):
|
|||||||
|
|
||||||
@torch.no_grad()
|
@torch.no_grad()
|
||||||
def decode_first_stage(self, latents):
|
def decode_first_stage(self, latents):
|
||||||
latents = latents.permute(0, 2, 1, 3, 4)
|
_, dtype = self.get_function_info(self.first_stage_model, 'decode')
|
||||||
latents = 1 / self.first_stage_model['paras']['scaling_factor_image'] * latents
|
with torch.autocast('cuda',
|
||||||
frames = get_model(self.first_stage_model).decode(latents)
|
enabled=dtype in ('bfloat16'),
|
||||||
|
dtype=getattr(torch, dtype)):
|
||||||
|
latents = latents.permute(0, 2, 1, 3, 4)
|
||||||
|
latents = 1 / self.first_stage_model['paras']['scaling_factor_image'] * latents
|
||||||
|
frames = get_model(self.first_stage_model).decode(latents)
|
||||||
return frames
|
return frames
|
||||||
|
|
||||||
def _prepare_rotary_positional_embeddings(
|
def _prepare_rotary_positional_embeddings(
|
||||||
@@ -121,8 +124,9 @@ class CogVideoXInference(DiffusionInference):
|
|||||||
)
|
)
|
||||||
function_name, dtype = self.get_function_info(
|
function_name, dtype = self.get_function_info(
|
||||||
self.diffusion_model)
|
self.diffusion_model)
|
||||||
|
|
||||||
with torch.autocast('cuda',
|
with torch.autocast('cuda',
|
||||||
enabled=dtype=='bfloat16',
|
enabled=dtype in ('float16', 'bfloat16'),
|
||||||
dtype=getattr(torch, dtype)):
|
dtype=getattr(torch, dtype)):
|
||||||
solver_sample = value_input.get('sample', 'ddim')
|
solver_sample = value_input.get('sample', 'ddim')
|
||||||
sample_steps = value_input.get('sample_steps', 50)
|
sample_steps = value_input.get('sample_steps', 50)
|
||||||
@@ -143,7 +147,6 @@ class CogVideoXInference(DiffusionInference):
|
|||||||
}],
|
}],
|
||||||
steps=sample_steps,
|
steps=sample_steps,
|
||||||
show_progress=True,
|
show_progress=True,
|
||||||
use_dynamic_cfg=True,
|
|
||||||
guide_scale=guide_scale,
|
guide_scale=guide_scale,
|
||||||
guide_rescale=guide_rescale,
|
guide_rescale=guide_rescale,
|
||||||
return_intermediate=None,
|
return_intermediate=None,
|
||||||
@@ -151,7 +154,6 @@ class CogVideoXInference(DiffusionInference):
|
|||||||
self.dynamic_unload(self.diffusion_model,
|
self.dynamic_unload(self.diffusion_model,
|
||||||
'diffusion_model',
|
'diffusion_model',
|
||||||
skip_loaded=True)
|
skip_loaded=True)
|
||||||
|
|
||||||
self.dynamic_load(self.first_stage_model, 'first_stage_model')
|
self.dynamic_load(self.first_stage_model, 'first_stage_model')
|
||||||
x_samples = self.decode_first_stage(latent).float() # [B, C, F, H, W]
|
x_samples = self.decode_first_stage(latent).float() # [B, C, F, H, W]
|
||||||
self.dynamic_unload(self.first_stage_model,
|
self.dynamic_unload(self.first_stage_model,
|
||||||
|
|||||||
@@ -97,7 +97,7 @@ class DiffusionInference():
|
|||||||
if 'weights_only' in torch.load.__code__.co_varnames:
|
if 'weights_only' in torch.load.__code__.co_varnames:
|
||||||
sd = torch.load(local_path, map_location='cpu', weights_only=True)
|
sd = torch.load(local_path, map_location='cpu', weights_only=True)
|
||||||
else:
|
else:
|
||||||
sd = torch.load(local_path, map_location='cpu')
|
sd = torch.load(local_path, map_location='cpu', weights_only=True)
|
||||||
first_stage_model_path = os.path.join(
|
first_stage_model_path = os.path.join(
|
||||||
os.path.dirname(local_path), 'first_stage_model.pth')
|
os.path.dirname(local_path), 'first_stage_model.pth')
|
||||||
cond_stage_model_path = os.path.join(
|
cond_stage_model_path = os.path.join(
|
||||||
@@ -203,7 +203,7 @@ class DiffusionInference():
|
|||||||
from safetensors.torch import load_file as load_safetensors
|
from safetensors.torch import load_file as load_safetensors
|
||||||
sd = load_safetensors(path)
|
sd = load_safetensors(path)
|
||||||
else:
|
else:
|
||||||
sd = torch.load(path, map_location='cpu')
|
sd = torch.load(path, map_location='cpu', weights_only=True)
|
||||||
|
|
||||||
new_sd = OrderedDict()
|
new_sd = OrderedDict()
|
||||||
for k, v in sd.items():
|
for k, v in sd.items():
|
||||||
@@ -230,16 +230,22 @@ class DiffusionInference():
|
|||||||
|
|
||||||
def load(self, module):
|
def load(self, module):
|
||||||
if module['device'] == 'offline':
|
if module['device'] == 'offline':
|
||||||
if module['cfg'].NAME in MODELS.class_map:
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
if (LazyImportModule.get_module_type(('MODELS', module['cfg'].NAME)) or
|
||||||
|
module['cfg'].NAME in MODELS.class_map):
|
||||||
model = MODELS.build(module['cfg'], logger=self.logger).eval()
|
model = MODELS.build(module['cfg'], logger=self.logger).eval()
|
||||||
elif module['cfg'].NAME in BACKBONES.class_map:
|
elif (LazyImportModule.get_module_type(('BACKBONES', module['cfg'].NAME)) or
|
||||||
|
module['cfg'].NAME in BACKBONES.class_map):
|
||||||
model = BACKBONES.build(module['cfg'],
|
model = BACKBONES.build(module['cfg'],
|
||||||
logger=self.logger).eval()
|
logger=self.logger).eval()
|
||||||
elif module['cfg'].NAME in EMBEDDERS.class_map:
|
elif (LazyImportModule.get_module_type(('EMBEDDERS', module['cfg'].NAME)) or
|
||||||
|
module['cfg'].NAME in EMBEDDERS.class_map):
|
||||||
model = EMBEDDERS.build(module['cfg'],
|
model = EMBEDDERS.build(module['cfg'],
|
||||||
logger=self.logger).eval()
|
logger=self.logger).eval()
|
||||||
else:
|
else:
|
||||||
raise NotImplementedError
|
raise NotImplementedError
|
||||||
|
if 'DTYPE' in module['cfg'] and module['cfg']['DTYPE'] is not None:
|
||||||
|
model = model.to(getattr(torch, module['cfg'].DTYPE))
|
||||||
if module['cfg'].get('RELOAD_MODEL', None):
|
if module['cfg'].get('RELOAD_MODEL', None):
|
||||||
self.init_from_ckpt(module['cfg'].RELOAD_MODEL, model)
|
self.init_from_ckpt(module['cfg'].RELOAD_MODEL, model)
|
||||||
module['model'] = model
|
module['model'] = model
|
||||||
@@ -268,8 +274,9 @@ class DiffusionInference():
|
|||||||
module['device'] = 'cpu'
|
module['device'] = 'cpu'
|
||||||
else:
|
else:
|
||||||
module['device'] = 'offline'
|
module['device'] = 'offline'
|
||||||
torch.cuda.empty_cache()
|
if torch.cuda.is_available():
|
||||||
torch.cuda.ipc_collect()
|
torch.cuda.empty_cache()
|
||||||
|
torch.cuda.ipc_collect()
|
||||||
return module
|
return module
|
||||||
|
|
||||||
def dynamic_load(self, module=None, name=''):
|
def dynamic_load(self, module=None, name=''):
|
||||||
|
|||||||
@@ -43,7 +43,7 @@ class LargenInference(DiffusionInference):
|
|||||||
if 'weights_only' in torch.load.__code__.co_varnames:
|
if 'weights_only' in torch.load.__code__.co_varnames:
|
||||||
sd = torch.load(local_path, map_location='cpu', weights_only=True)
|
sd = torch.load(local_path, map_location='cpu', weights_only=True)
|
||||||
else:
|
else:
|
||||||
sd = torch.load(local_path, map_location='cpu')
|
sd = torch.load(local_path, map_location='cpu', weights_only=True)
|
||||||
if 'model' in sd:
|
if 'model' in sd:
|
||||||
sd = sd['model']
|
sd = sd['model']
|
||||||
|
|
||||||
|
|||||||
@@ -144,9 +144,9 @@ class TunerInference():
|
|||||||
is_bin_file = True
|
is_bin_file = True
|
||||||
if os.path.isfile(bin_file):
|
if os.path.isfile(bin_file):
|
||||||
if 'weights_only' in torch.load.__code__.co_varnames:
|
if 'weights_only' in torch.load.__code__.co_varnames:
|
||||||
state_dict = torch.load(bin_file, weights_only=True)
|
state_dict = torch.load(bin_file, weights_only=True, map_location="cpu")
|
||||||
else:
|
else:
|
||||||
state_dict = torch.load(bin_file)
|
state_dict = torch.load(bin_file, map_location="cpu")
|
||||||
elif os.path.isfile(safe_file):
|
elif os.path.isfile(safe_file):
|
||||||
is_bin_file = False
|
is_bin_file = False
|
||||||
from safetensors.torch import \
|
from safetensors.torch import \
|
||||||
|
|||||||
@@ -1,5 +1,23 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
from typing import TYPE_CHECKING
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
from scepter.modules.model import (backbone, embedder, head, loss, metric,
|
|
||||||
neck, network, tokenizer, tuner, diffusion)
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.model import (backbone, embedder, head, loss, metric,
|
||||||
|
neck, network, tokenizer, tuner, diffusion)
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'model': ['backbone', 'embedder', 'head', 'loss', 'metric',
|
||||||
|
'neck', 'network', 'tokenizer', 'tuner', 'diffusion']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -1,4 +1,23 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.model.backbone import (ace, autoencoder, flux, image, cogvideox,
|
from typing import TYPE_CHECKING
|
||||||
mmdit, pixart, unet, utils, video)
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.model.backbone import (ace, autoencoder, flux, image, cogvideox,
|
||||||
|
mmdit, pixart, unet, utils, video)
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'backbone': ['ace', 'autoencoder', 'flux', 'image', 'cogvideox',
|
||||||
|
'mmdit', 'pixart', 'unet', 'utils', 'video']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -151,7 +151,7 @@ class ACE(BaseModel):
|
|||||||
def load_pretrained_model(self, pretrained_model):
|
def load_pretrained_model(self, pretrained_model):
|
||||||
if pretrained_model:
|
if pretrained_model:
|
||||||
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
||||||
model = torch.load(local_path, map_location='cpu')
|
model = torch.load(local_path, map_location='cpu', weights_only=True)
|
||||||
if 'state_dict' in model:
|
if 'state_dict' in model:
|
||||||
model = model['state_dict']
|
model = model['state_dict']
|
||||||
new_ckpt = OrderedDict()
|
new_ckpt = OrderedDict()
|
||||||
|
|||||||
@@ -0,0 +1,2 @@
|
|||||||
|
# -*- coding: utf-8 -*-
|
||||||
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
@@ -0,0 +1,97 @@
|
|||||||
|
# -*- coding: utf-8 -*-
|
||||||
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
import torch
|
||||||
|
from torch.nn.utils.rnn import pad_sequence
|
||||||
|
|
||||||
|
from einops import rearrange
|
||||||
|
from scepter.modules.model.backbone.flux import FluxMR
|
||||||
|
from scepter.modules.model.registry import BACKBONES
|
||||||
|
from scepter.modules.utils.config import dict_to_yaml
|
||||||
|
|
||||||
|
|
||||||
|
@BACKBONES.register_class()
|
||||||
|
class FluxMRACEPlus(FluxMR):
|
||||||
|
def __init__(self, cfg, logger=None):
|
||||||
|
super().__init__(cfg, logger)
|
||||||
|
|
||||||
|
def prepare_input(self, x, cond):
|
||||||
|
context, y = cond['context'], cond['y']
|
||||||
|
batch_frames, batch_frames_ids = [], []
|
||||||
|
for ix, shape, imask, ie, ie_mask in zip(x, cond['x_shapes'],
|
||||||
|
cond['x_mask'], cond['edit'],
|
||||||
|
cond['edit_mask']):
|
||||||
|
# unpack image from sequence
|
||||||
|
ix = ix[:, :shape[0] * shape[1]].view(-1, shape[0], shape[1])
|
||||||
|
imask = torch.ones_like(
|
||||||
|
ix[[0], :, :]) if imask is None else imask.squeeze(0)
|
||||||
|
if len(ie) > 0:
|
||||||
|
ie = [iie.squeeze(0) for iie in ie]
|
||||||
|
ie_mask = [
|
||||||
|
torch.ones(
|
||||||
|
(ix.shape[0] * 4, ix.shape[1],
|
||||||
|
ix.shape[2])) if iime is None else iime.squeeze(0)
|
||||||
|
for iime in ie_mask
|
||||||
|
]
|
||||||
|
ie = torch.cat(ie, dim=-1)
|
||||||
|
ie_mask = torch.cat(ie_mask, dim=-1)
|
||||||
|
else:
|
||||||
|
ie, ie_mask = torch.zeros_like(ix).to(x), torch.ones_like(
|
||||||
|
imask).to(x)
|
||||||
|
ix = torch.cat([ix, ie, ie_mask], dim=0)
|
||||||
|
c, h, w = ix.shape
|
||||||
|
ix = rearrange(ix,
|
||||||
|
'c (h ph) (w pw) -> (h w) (c ph pw)',
|
||||||
|
ph=2,
|
||||||
|
pw=2)
|
||||||
|
ix_id = torch.zeros(h // 2, w // 2, 3)
|
||||||
|
ix_id[..., 1] = ix_id[..., 1] + torch.arange(h // 2)[:, None]
|
||||||
|
ix_id[..., 2] = ix_id[..., 2] + torch.arange(w // 2)[None, :]
|
||||||
|
ix_id = rearrange(ix_id, 'h w c -> (h w) c')
|
||||||
|
batch_frames.append([ix])
|
||||||
|
batch_frames_ids.append([ix_id])
|
||||||
|
x_list, x_id_list, mask_x_list, x_seq_length = [], [], [], []
|
||||||
|
for frames, frame_ids in zip(batch_frames, batch_frames_ids):
|
||||||
|
proj_frames = []
|
||||||
|
for idx, one_frame in enumerate(frames):
|
||||||
|
one_frame = self.img_in(one_frame)
|
||||||
|
proj_frames.append(one_frame)
|
||||||
|
ix = torch.cat(proj_frames, dim=0)
|
||||||
|
if_id = torch.cat(frame_ids, dim=0)
|
||||||
|
x_list.append(ix)
|
||||||
|
x_id_list.append(if_id)
|
||||||
|
mask_x_list.append(
|
||||||
|
torch.ones(ix.shape[0]).to(ix.device,
|
||||||
|
non_blocking=True).bool())
|
||||||
|
x_seq_length.append(ix.shape[0])
|
||||||
|
# if len(x_list) < 1: import pdb;pdb.set_trace()
|
||||||
|
x = pad_sequence(tuple(x_list), batch_first=True)
|
||||||
|
x_ids = pad_sequence(tuple(x_id_list), batch_first=True).to(
|
||||||
|
x) # [b,pad_seq,2] pad (0.,0.) at dim2
|
||||||
|
mask_x = pad_sequence(tuple(mask_x_list), batch_first=True)
|
||||||
|
# import pdb;pdb.set_trace()
|
||||||
|
if isinstance(context, list):
|
||||||
|
txt_list, mask_txt_list, y_list = [], [], []
|
||||||
|
for sample_id, (ctx, yy) in enumerate(zip(context, y)):
|
||||||
|
txt_list.append(self.txt_in(ctx.to(x)))
|
||||||
|
mask_txt_list.append(
|
||||||
|
torch.ones(txt_list[-1].shape[0]).to(
|
||||||
|
ctx.device, non_blocking=True).bool())
|
||||||
|
y_list.append(yy.to(x))
|
||||||
|
txt = pad_sequence(tuple(txt_list), batch_first=True)
|
||||||
|
txt_ids = torch.zeros(txt.shape[0], txt.shape[1], 3).to(x)
|
||||||
|
mask_txt = pad_sequence(tuple(mask_txt_list), batch_first=True)
|
||||||
|
y = torch.cat(y_list, dim=0)
|
||||||
|
assert y.ndim == 2 and txt.ndim == 3
|
||||||
|
else:
|
||||||
|
txt = self.txt_in(context)
|
||||||
|
txt_ids = torch.zeros(context.shape[0], context.shape[1], 3).to(x)
|
||||||
|
mask_txt = torch.ones(context.shape[0], context.shape[1]).to(
|
||||||
|
x.device, non_blocking=True).bool()
|
||||||
|
return x, x_ids, txt, txt_ids, y, mask_x, mask_txt, x_seq_length
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def get_config_template():
|
||||||
|
return dict_to_yaml('MODEL',
|
||||||
|
__class__.__name__,
|
||||||
|
FluxMRACEPlus.para_dict,
|
||||||
|
set_name=True)
|
||||||
@@ -48,6 +48,8 @@ class CogVideoXTransformer3DModel(BaseModel):
|
|||||||
Whether to flip the sin to cos in the time embedding.
|
Whether to flip the sin to cos in the time embedding.
|
||||||
time_embed_dim (`int`, defaults to `512`):
|
time_embed_dim (`int`, defaults to `512`):
|
||||||
Output dimension of timestep embeddings.
|
Output dimension of timestep embeddings.
|
||||||
|
ofs_embed_dim (`int`, defaults to `512`):
|
||||||
|
Output dimension of "ofs" embeddings used in CogVideoX-5b-I2B in version 1.5
|
||||||
text_embed_dim (`int`, defaults to `4096`):
|
text_embed_dim (`int`, defaults to `4096`):
|
||||||
Input dimension of text embeddings from the text encoder.
|
Input dimension of text embeddings from the text encoder.
|
||||||
num_layers (`int`, defaults to `30`):
|
num_layers (`int`, defaults to `30`):
|
||||||
@@ -98,6 +100,7 @@ class CogVideoXTransformer3DModel(BaseModel):
|
|||||||
flip_sin_to_cos = cfg.get("FLIP_SIN_TO_COS", True)
|
flip_sin_to_cos = cfg.get("FLIP_SIN_TO_COS", True)
|
||||||
freq_shift = cfg.get("FREQ_SHIFT", 0)
|
freq_shift = cfg.get("FREQ_SHIFT", 0)
|
||||||
time_embed_dim = cfg.get("TIME_EMBED_DIM", 512)
|
time_embed_dim = cfg.get("TIME_EMBED_DIM", 512)
|
||||||
|
ofs_embed_dim = cfg.get("OFS_EMBED_DIM", None) # 1.5
|
||||||
text_embed_dim = cfg.get("TEXT_EMBED_DIM", 4096)
|
text_embed_dim = cfg.get("TEXT_EMBED_DIM", 4096)
|
||||||
num_layers = cfg.get("NUM_LAYERS", 30)
|
num_layers = cfg.get("NUM_LAYERS", 30)
|
||||||
dropout = cfg.get("DROPOUT", 0.0)
|
dropout = cfg.get("DROPOUT", 0.0)
|
||||||
@@ -106,6 +109,8 @@ class CogVideoXTransformer3DModel(BaseModel):
|
|||||||
sample_height = cfg.get("SAMPLE_HEIGHT", 60)
|
sample_height = cfg.get("SAMPLE_HEIGHT", 60)
|
||||||
sample_frames = cfg.get("SAMPLE_FRAMES", 49)
|
sample_frames = cfg.get("SAMPLE_FRAMES", 49)
|
||||||
patch_size = cfg.get("PATCH_SIZE", 2)
|
patch_size = cfg.get("PATCH_SIZE", 2)
|
||||||
|
patch_size_t = cfg.get("PATCH_SIZE_T", None)
|
||||||
|
patch_bias = cfg.get("PATCH_BIAS", True)
|
||||||
temporal_compression_ratio = cfg.get("TEMPORAL_COMPRESSION_RATIO", 4)
|
temporal_compression_ratio = cfg.get("TEMPORAL_COMPRESSION_RATIO", 4)
|
||||||
max_text_seq_length = cfg.get("MAX_TEXT_SEQ_LENGTH", 226)
|
max_text_seq_length = cfg.get("MAX_TEXT_SEQ_LENGTH", 226)
|
||||||
activation_fn = cfg.get("ACTIVATION_FN", "gelu-approximate")
|
activation_fn = cfg.get("ACTIVATION_FN", "gelu-approximate")
|
||||||
@@ -119,6 +124,7 @@ class CogVideoXTransformer3DModel(BaseModel):
|
|||||||
self.gradient_checkpointing = cfg.get("GRADIENT_CHECKPOINTING", False)
|
self.gradient_checkpointing = cfg.get("GRADIENT_CHECKPOINTING", False)
|
||||||
inner_dim = num_attention_heads * attention_head_dim
|
inner_dim = num_attention_heads * attention_head_dim
|
||||||
self.patch_size = patch_size
|
self.patch_size = patch_size
|
||||||
|
self.patch_size_t = patch_size_t
|
||||||
self.use_rotary_positional_embeddings = use_rotary_positional_embeddings
|
self.use_rotary_positional_embeddings = use_rotary_positional_embeddings
|
||||||
|
|
||||||
if not use_rotary_positional_embeddings and use_learned_positional_embeddings:
|
if not use_rotary_positional_embeddings and use_learned_positional_embeddings:
|
||||||
@@ -131,10 +137,11 @@ class CogVideoXTransformer3DModel(BaseModel):
|
|||||||
# 1. Patch embedding
|
# 1. Patch embedding
|
||||||
self.patch_embed = CogVideoXPatchEmbed(
|
self.patch_embed = CogVideoXPatchEmbed(
|
||||||
patch_size=patch_size,
|
patch_size=patch_size,
|
||||||
|
patch_size_t=patch_size_t,
|
||||||
in_channels=in_channels,
|
in_channels=in_channels,
|
||||||
embed_dim=inner_dim,
|
embed_dim=inner_dim,
|
||||||
text_embed_dim=text_embed_dim,
|
text_embed_dim=text_embed_dim,
|
||||||
bias=True,
|
bias=patch_bias,
|
||||||
sample_width=sample_width,
|
sample_width=sample_width,
|
||||||
sample_height=sample_height,
|
sample_height=sample_height,
|
||||||
sample_frames=sample_frames,
|
sample_frames=sample_frames,
|
||||||
@@ -147,10 +154,18 @@ class CogVideoXTransformer3DModel(BaseModel):
|
|||||||
)
|
)
|
||||||
self.embedding_dropout = nn.Dropout(dropout)
|
self.embedding_dropout = nn.Dropout(dropout)
|
||||||
|
|
||||||
# 2. Time embeddings
|
# 2. Time embeddings and ofs embedding(Only CogVideoX1.5-5B I2V have)
|
||||||
self.time_proj = Timesteps(inner_dim, flip_sin_to_cos, freq_shift)
|
self.time_proj = Timesteps(inner_dim, flip_sin_to_cos, freq_shift)
|
||||||
self.time_embedding = TimestepEmbedding(inner_dim, time_embed_dim, timestep_activation_fn)
|
self.time_embedding = TimestepEmbedding(inner_dim, time_embed_dim, timestep_activation_fn)
|
||||||
|
|
||||||
|
self.ofs_proj = None
|
||||||
|
self.ofs_embedding = None
|
||||||
|
if ofs_embed_dim:
|
||||||
|
self.ofs_proj = Timesteps(ofs_embed_dim, flip_sin_to_cos, freq_shift)
|
||||||
|
self.ofs_embedding = TimestepEmbedding(
|
||||||
|
ofs_embed_dim, ofs_embed_dim, timestep_activation_fn
|
||||||
|
) # same as time embeddings, for ofs
|
||||||
|
|
||||||
# 3. Define spatio-temporal transformers blocks
|
# 3. Define spatio-temporal transformers blocks
|
||||||
self.transformer_blocks = nn.ModuleList(
|
self.transformer_blocks = nn.ModuleList(
|
||||||
[
|
[
|
||||||
@@ -178,7 +193,15 @@ class CogVideoXTransformer3DModel(BaseModel):
|
|||||||
norm_eps=norm_eps,
|
norm_eps=norm_eps,
|
||||||
chunk_dim=1,
|
chunk_dim=1,
|
||||||
)
|
)
|
||||||
self.proj_out = nn.Linear(inner_dim, patch_size * patch_size * out_channels)
|
|
||||||
|
if patch_size_t is None:
|
||||||
|
# For CogVideox 1.0
|
||||||
|
output_dim = patch_size * patch_size * out_channels
|
||||||
|
else:
|
||||||
|
# For CogVideoX 1.5
|
||||||
|
output_dim = patch_size * patch_size * patch_size_t * out_channels
|
||||||
|
|
||||||
|
self.proj_out = nn.Linear(inner_dim, output_dim)
|
||||||
|
|
||||||
def forward(
|
def forward(
|
||||||
self,
|
self,
|
||||||
@@ -186,6 +209,7 @@ class CogVideoXTransformer3DModel(BaseModel):
|
|||||||
t: Union[int, float, torch.LongTensor] = None,
|
t: Union[int, float, torch.LongTensor] = None,
|
||||||
cond: torch.Tensor = None,
|
cond: torch.Tensor = None,
|
||||||
timestep_cond: Optional[torch.Tensor] = None,
|
timestep_cond: Optional[torch.Tensor] = None,
|
||||||
|
ofs: Optional[Union[int, float, torch.LongTensor]] = None,
|
||||||
image_rotary_emb: Optional[Tuple[torch.Tensor, torch.Tensor]] = None,
|
image_rotary_emb: Optional[Tuple[torch.Tensor, torch.Tensor]] = None,
|
||||||
**kwargs
|
**kwargs
|
||||||
):
|
):
|
||||||
@@ -208,6 +232,12 @@ class CogVideoXTransformer3DModel(BaseModel):
|
|||||||
t_emb = t_emb.to(dtype=encoder_hidden_states.dtype)
|
t_emb = t_emb.to(dtype=encoder_hidden_states.dtype)
|
||||||
emb = self.time_embedding(t_emb, timestep_cond)
|
emb = self.time_embedding(t_emb, timestep_cond)
|
||||||
|
|
||||||
|
if self.ofs_embedding is not None:
|
||||||
|
ofs_emb = self.ofs_proj(ofs)
|
||||||
|
ofs_emb = ofs_emb.to(dtype=hidden_states.dtype)
|
||||||
|
ofs_emb = self.ofs_embedding(ofs_emb)
|
||||||
|
emb = emb + ofs_emb
|
||||||
|
|
||||||
# 2. Patch embedding
|
# 2. Patch embedding
|
||||||
hidden_states = self.patch_embed(encoder_hidden_states, hidden_states)
|
hidden_states = self.patch_embed(encoder_hidden_states, hidden_states)
|
||||||
hidden_states = self.embedding_dropout(hidden_states)
|
hidden_states = self.embedding_dropout(hidden_states)
|
||||||
@@ -261,8 +291,16 @@ class CogVideoXTransformer3DModel(BaseModel):
|
|||||||
# - It is okay to `channels` use for CogVideoX-2b and CogVideoX-5b (number of input channels is equal to output channels)
|
# - It is okay to `channels` use for CogVideoX-2b and CogVideoX-5b (number of input channels is equal to output channels)
|
||||||
# - However, for CogVideoX-5b-I2V also takes concatenated input image latents (number of input channels is twice the output channels)
|
# - However, for CogVideoX-5b-I2V also takes concatenated input image latents (number of input channels is twice the output channels)
|
||||||
p = self.patch_size
|
p = self.patch_size
|
||||||
output = hidden_states.reshape(batch_size, num_frames, height // p, width // p, -1, p, p)
|
p_t = self.patch_size_t
|
||||||
output = output.permute(0, 1, 4, 2, 5, 3, 6).flatten(5, 6).flatten(3, 4)
|
|
||||||
|
if p_t is None:
|
||||||
|
output = hidden_states.reshape(batch_size, num_frames, height // p, width // p, -1, p, p)
|
||||||
|
output = output.permute(0, 1, 4, 2, 5, 3, 6).flatten(5, 6).flatten(3, 4)
|
||||||
|
else:
|
||||||
|
output = hidden_states.reshape(
|
||||||
|
batch_size, (num_frames + p_t - 1) // p_t, height // p, width // p, -1, p_t, p, p
|
||||||
|
)
|
||||||
|
output = output.permute(0, 1, 5, 4, 2, 6, 3, 7).flatten(6, 7).flatten(4, 5).flatten(1, 2)
|
||||||
|
|
||||||
return output
|
return output
|
||||||
|
|
||||||
@@ -277,7 +315,7 @@ class CogVideoXTransformer3DModel(BaseModel):
|
|||||||
from safetensors.torch import load_file as load_safetensors
|
from safetensors.torch import load_file as load_safetensors
|
||||||
ckpt = load_safetensors(local_model)
|
ckpt = load_safetensors(local_model)
|
||||||
else:
|
else:
|
||||||
ckpt = torch.load(local_model, map_location='cpu')
|
ckpt = torch.load(local_model, map_location='cpu', weights_only=True)
|
||||||
ckpt_all.update(ckpt)
|
ckpt_all.update(ckpt)
|
||||||
missing, unexpected = self.load_state_dict(ckpt_all, strict=False)
|
missing, unexpected = self.load_state_dict(ckpt_all, strict=False)
|
||||||
if we.rank == 0:
|
if we.rank == 0:
|
||||||
@@ -309,9 +347,9 @@ if __name__ == "__main__":
|
|||||||
FS.init_fs_client(file_sys)
|
FS.init_fs_client(file_sys)
|
||||||
model = BACKBONES.build(cfg.DIFFUSION_MODEL, logger=get_logger()).eval().requires_grad_(False).to('cuda').to(torch.bfloat16)
|
model = BACKBONES.build(cfg.DIFFUSION_MODEL, logger=get_logger()).eval().requires_grad_(False).to('cuda').to(torch.bfloat16)
|
||||||
|
|
||||||
hidden_states = torch.load(FS.get_from(cfg.HIDDEN_STATES))
|
hidden_states = torch.load(FS.get_from(cfg.HIDDEN_STATES), weights_only=True)
|
||||||
encoder_hidden_states = torch.load(FS.get_from(cfg.ENCODER_HIDDEN_STATES))
|
encoder_hidden_states = torch.load(FS.get_from(cfg.ENCODER_HIDDEN_STATES), weights_only=True)
|
||||||
timestep = torch.load(FS.get_from(cfg.TIMESTEP))
|
timestep = torch.load(FS.get_from(cfg.TIMESTEP), weights_only=True)
|
||||||
timestep_cond = None
|
timestep_cond = None
|
||||||
image_rotary_emb = None
|
image_rotary_emb = None
|
||||||
attention_kwargs = None
|
attention_kwargs = None
|
||||||
|
|||||||
@@ -178,6 +178,7 @@ class CogVideoXPatchEmbed(nn.Module):
|
|||||||
def __init__(
|
def __init__(
|
||||||
self,
|
self,
|
||||||
patch_size: int = 2,
|
patch_size: int = 2,
|
||||||
|
patch_size_t: Optional[int] = None,
|
||||||
in_channels: int = 16,
|
in_channels: int = 16,
|
||||||
embed_dim: int = 1920,
|
embed_dim: int = 1920,
|
||||||
text_embed_dim: int = 4096,
|
text_embed_dim: int = 4096,
|
||||||
@@ -195,6 +196,7 @@ class CogVideoXPatchEmbed(nn.Module):
|
|||||||
super().__init__()
|
super().__init__()
|
||||||
|
|
||||||
self.patch_size = patch_size
|
self.patch_size = patch_size
|
||||||
|
self.patch_size_t = patch_size_t
|
||||||
self.embed_dim = embed_dim
|
self.embed_dim = embed_dim
|
||||||
self.sample_height = sample_height
|
self.sample_height = sample_height
|
||||||
self.sample_width = sample_width
|
self.sample_width = sample_width
|
||||||
@@ -206,9 +208,15 @@ class CogVideoXPatchEmbed(nn.Module):
|
|||||||
self.use_positional_embeddings = use_positional_embeddings
|
self.use_positional_embeddings = use_positional_embeddings
|
||||||
self.use_learned_positional_embeddings = use_learned_positional_embeddings
|
self.use_learned_positional_embeddings = use_learned_positional_embeddings
|
||||||
|
|
||||||
self.proj = nn.Conv2d(
|
if patch_size_t is None:
|
||||||
in_channels, embed_dim, kernel_size=(patch_size, patch_size), stride=patch_size, bias=bias
|
# CogVideoX 1.0 checkpoints
|
||||||
)
|
self.proj = nn.Conv2d(
|
||||||
|
in_channels, embed_dim, kernel_size=(patch_size, patch_size), stride=patch_size, bias=bias
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
# CogVideoX 1.5 checkpoints
|
||||||
|
self.proj = nn.Linear(in_channels * patch_size * patch_size * patch_size_t, embed_dim)
|
||||||
|
|
||||||
self.text_proj = nn.Linear(text_embed_dim, embed_dim)
|
self.text_proj = nn.Linear(text_embed_dim, embed_dim)
|
||||||
|
|
||||||
if use_positional_embeddings or use_learned_positional_embeddings:
|
if use_positional_embeddings or use_learned_positional_embeddings:
|
||||||
@@ -247,12 +255,24 @@ class CogVideoXPatchEmbed(nn.Module):
|
|||||||
"""
|
"""
|
||||||
text_embeds = self.text_proj(text_embeds)
|
text_embeds = self.text_proj(text_embeds)
|
||||||
|
|
||||||
batch, num_frames, channels, height, width = image_embeds.shape
|
batch_size, num_frames, channels, height, width = image_embeds.shape
|
||||||
image_embeds = image_embeds.reshape(-1, channels, height, width)
|
|
||||||
image_embeds = self.proj(image_embeds)
|
if self.patch_size_t is None:
|
||||||
image_embeds = image_embeds.view(batch, num_frames, *image_embeds.shape[1:])
|
image_embeds = image_embeds.reshape(-1, channels, height, width)
|
||||||
image_embeds = image_embeds.flatten(3).transpose(2, 3) # [batch, num_frames, height x width, channels]
|
image_embeds = self.proj(image_embeds)
|
||||||
image_embeds = image_embeds.flatten(1, 2) # [batch, num_frames x height x width, channels]
|
image_embeds = image_embeds.view(batch_size, num_frames, *image_embeds.shape[1:])
|
||||||
|
image_embeds = image_embeds.flatten(3).transpose(2, 3) # [batch, num_frames, height x width, channels]
|
||||||
|
image_embeds = image_embeds.flatten(1, 2) # [batch, num_frames x height x width, channels]
|
||||||
|
else:
|
||||||
|
p = self.patch_size
|
||||||
|
p_t = self.patch_size_t
|
||||||
|
|
||||||
|
image_embeds = image_embeds.permute(0, 1, 3, 4, 2)
|
||||||
|
image_embeds = image_embeds.reshape(
|
||||||
|
batch_size, num_frames // p_t, p_t, height // p, p, width // p, p, channels
|
||||||
|
)
|
||||||
|
image_embeds = image_embeds.permute(0, 1, 3, 5, 7, 2, 4, 6).flatten(4, 7).flatten(1, 3)
|
||||||
|
image_embeds = self.proj(image_embeds)
|
||||||
|
|
||||||
embeds = torch.cat(
|
embeds = torch.cat(
|
||||||
[text_embeds, image_embeds], dim=1
|
[text_embeds, image_embeds], dim=1
|
||||||
|
|||||||
@@ -459,7 +459,14 @@ def get_1d_rotary_pos_embed(
|
|||||||
|
|
||||||
|
|
||||||
def get_3d_rotary_pos_embed(
|
def get_3d_rotary_pos_embed(
|
||||||
embed_dim, crops_coords, grid_size, temporal_size, theta: int = 10000, use_real: bool = True
|
embed_dim,
|
||||||
|
crops_coords,
|
||||||
|
grid_size,
|
||||||
|
temporal_size,
|
||||||
|
theta: int = 10000,
|
||||||
|
use_real: bool = True,
|
||||||
|
grid_type: str = "linspace",
|
||||||
|
max_size: Optional[Tuple[int, int]] = None,
|
||||||
) -> Union[torch.Tensor, Tuple[torch.Tensor, torch.Tensor]]:
|
) -> Union[torch.Tensor, Tuple[torch.Tensor, torch.Tensor]]:
|
||||||
"""
|
"""
|
||||||
RoPE for video tokens with 3D structure.
|
RoPE for video tokens with 3D structure.
|
||||||
@@ -475,17 +482,30 @@ def get_3d_rotary_pos_embed(
|
|||||||
The size of the temporal dimension.
|
The size of the temporal dimension.
|
||||||
theta (`float`):
|
theta (`float`):
|
||||||
Scaling factor for frequency computation.
|
Scaling factor for frequency computation.
|
||||||
|
grid_type (`str`):
|
||||||
|
Whether to use "linspace" or "slice" to compute grids.
|
||||||
|
|
||||||
Returns:
|
Returns:
|
||||||
`torch.Tensor`: positional embedding with shape `(temporal_size * grid_size[0] * grid_size[1], embed_dim/2)`.
|
`torch.Tensor`: positional embedding with shape `(temporal_size * grid_size[0] * grid_size[1], embed_dim/2)`.
|
||||||
"""
|
"""
|
||||||
if use_real is not True:
|
if use_real is not True:
|
||||||
raise ValueError(" `use_real = False` is not currently supported for get_3d_rotary_pos_embed")
|
raise ValueError(" `use_real = False` is not currently supported for get_3d_rotary_pos_embed")
|
||||||
start, stop = crops_coords
|
|
||||||
grid_size_h, grid_size_w = grid_size
|
if grid_type == "linspace":
|
||||||
grid_h = np.linspace(start[0], stop[0], grid_size_h, endpoint=False, dtype=np.float32)
|
start, stop = crops_coords
|
||||||
grid_w = np.linspace(start[1], stop[1], grid_size_w, endpoint=False, dtype=np.float32)
|
grid_size_h, grid_size_w = grid_size
|
||||||
grid_t = np.linspace(0, temporal_size, temporal_size, endpoint=False, dtype=np.float32)
|
grid_h = np.linspace(start[0], stop[0], grid_size_h, endpoint=False, dtype=np.float32)
|
||||||
|
grid_w = np.linspace(start[1], stop[1], grid_size_w, endpoint=False, dtype=np.float32)
|
||||||
|
grid_t = np.arange(temporal_size, dtype=np.float32)
|
||||||
|
grid_t = np.linspace(0, temporal_size, temporal_size, endpoint=False, dtype=np.float32)
|
||||||
|
elif grid_type == "slice":
|
||||||
|
max_h, max_w = max_size
|
||||||
|
grid_size_h, grid_size_w = grid_size
|
||||||
|
grid_h = np.arange(max_h, dtype=np.float32)
|
||||||
|
grid_w = np.arange(max_w, dtype=np.float32)
|
||||||
|
grid_t = np.arange(temporal_size, dtype=np.float32)
|
||||||
|
else:
|
||||||
|
raise ValueError("Invalid value passed for `grid_type`.")
|
||||||
|
|
||||||
# Compute dimensions for each axis
|
# Compute dimensions for each axis
|
||||||
dim_t = embed_dim // 4
|
dim_t = embed_dim // 4
|
||||||
@@ -521,6 +541,12 @@ def get_3d_rotary_pos_embed(
|
|||||||
t_cos, t_sin = freqs_t # both t_cos and t_sin has shape: temporal_size, dim_t
|
t_cos, t_sin = freqs_t # both t_cos and t_sin has shape: temporal_size, dim_t
|
||||||
h_cos, h_sin = freqs_h # both h_cos and h_sin has shape: grid_size_h, dim_h
|
h_cos, h_sin = freqs_h # both h_cos and h_sin has shape: grid_size_h, dim_h
|
||||||
w_cos, w_sin = freqs_w # both w_cos and w_sin has shape: grid_size_w, dim_w
|
w_cos, w_sin = freqs_w # both w_cos and w_sin has shape: grid_size_w, dim_w
|
||||||
|
|
||||||
|
if grid_type == "slice":
|
||||||
|
t_cos, t_sin = t_cos[:temporal_size], t_sin[:temporal_size]
|
||||||
|
h_cos, h_sin = h_cos[:grid_size_h], h_sin[:grid_size_h]
|
||||||
|
w_cos, w_sin = w_cos[:grid_size_w], w_sin[:grid_size_w]
|
||||||
|
|
||||||
cos = combine_time_height_width(t_cos, h_cos, w_cos)
|
cos = combine_time_height_width(t_cos, h_cos, w_cos)
|
||||||
sin = combine_time_height_width(t_sin, h_sin, w_sin)
|
sin = combine_time_height_width(t_sin, h_sin, w_sin)
|
||||||
return cos, sin
|
return cos, sin
|
||||||
|
|||||||
@@ -1,3 +1,3 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from .flux import Flux
|
from .flux import Flux, FluxMR, FluxMRFill, FluxMRRedux, FluxMRControl
|
||||||
|
|||||||
@@ -1,6 +1,9 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
# This file contains code that is adapted from
|
||||||
|
# https://github.com/black-forest-labs/flux.git
|
||||||
import math
|
import math
|
||||||
|
from collections import OrderedDict
|
||||||
from functools import partial
|
from functools import partial
|
||||||
|
|
||||||
import torch
|
import torch
|
||||||
@@ -15,8 +18,6 @@ from torch.utils.checkpoint import checkpoint_sequential
|
|||||||
from torch.nn.utils.rnn import pad_sequence
|
from torch.nn.utils.rnn import pad_sequence
|
||||||
from .layers import (DoubleStreamBlock, EmbedND, LastLayer, MLPEmbedder,
|
from .layers import (DoubleStreamBlock, EmbedND, LastLayer, MLPEmbedder,
|
||||||
SingleStreamBlock, timestep_embedding)
|
SingleStreamBlock, timestep_embedding)
|
||||||
|
|
||||||
|
|
||||||
@BACKBONES.register_class()
|
@BACKBONES.register_class()
|
||||||
class Flux(BaseModel):
|
class Flux(BaseModel):
|
||||||
"""
|
"""
|
||||||
@@ -98,7 +99,14 @@ class Flux(BaseModel):
|
|||||||
qkv_bias = cfg.QKV_BIAS
|
qkv_bias = cfg.QKV_BIAS
|
||||||
depth = cfg.DEPTH
|
depth = cfg.DEPTH
|
||||||
depth_single_blocks = cfg.DEPTH_SINGLE_BLOCKS
|
depth_single_blocks = cfg.DEPTH_SINGLE_BLOCKS
|
||||||
self.use_grad_checkpoint = cfg.get('USE_GRAD_CHECKPOINT', False)
|
self.use_grad_checkpoint = cfg.get("USE_GRAD_CHECKPOINT", False)
|
||||||
|
self.attn_backend = cfg.get("ATTN_BACKEND", "pytorch")
|
||||||
|
self.cache_pretrain_model = cfg.get("CACHE_PRETRAIN_MODEL", False)
|
||||||
|
self.lora_model = cfg.get("DIFFUSERS_LORA_MODEL", None)
|
||||||
|
self.comfyui_lora_model = cfg.get("COMFYUI_LORA_MODEL", None)
|
||||||
|
self.swift_lora_model = cfg.get("SWIFT_LORA_MODEL", None)
|
||||||
|
self.blackforest_lora_model = cfg.get("BLACKFOREST_LORA_MODEL", None)
|
||||||
|
self.pretrain_adapter = cfg.get("PRETRAIN_ADAPTER", None)
|
||||||
|
|
||||||
if hidden_size % num_heads != 0:
|
if hidden_size % num_heads != 0:
|
||||||
raise ValueError(
|
raise ValueError(
|
||||||
@@ -119,85 +127,350 @@ class Flux(BaseModel):
|
|||||||
if self.guidance_embed else nn.Identity())
|
if self.guidance_embed else nn.Identity())
|
||||||
self.txt_in = nn.Linear(context_in_dim, self.hidden_size)
|
self.txt_in = nn.Linear(context_in_dim, self.hidden_size)
|
||||||
|
|
||||||
self.double_blocks = nn.ModuleList([
|
self.double_blocks = nn.ModuleList(
|
||||||
DoubleStreamBlock(
|
[
|
||||||
self.hidden_size,
|
DoubleStreamBlock(
|
||||||
self.num_heads,
|
self.hidden_size,
|
||||||
mlp_ratio=mlp_ratio,
|
self.num_heads,
|
||||||
qkv_bias=qkv_bias,
|
mlp_ratio=mlp_ratio,
|
||||||
) for _ in range(depth)
|
qkv_bias=qkv_bias,
|
||||||
])
|
backend=self.attn_backend
|
||||||
|
)
|
||||||
|
for _ in range(depth)
|
||||||
|
]
|
||||||
|
)
|
||||||
|
|
||||||
self.single_blocks = nn.ModuleList([
|
self.single_blocks = nn.ModuleList(
|
||||||
SingleStreamBlock(self.hidden_size,
|
[
|
||||||
self.num_heads,
|
SingleStreamBlock(self.hidden_size, self.num_heads, mlp_ratio=mlp_ratio, backend=self.attn_backend)
|
||||||
mlp_ratio=mlp_ratio)
|
for _ in range(depth_single_blocks)
|
||||||
for _ in range(depth_single_blocks)
|
]
|
||||||
])
|
)
|
||||||
|
|
||||||
self.final_layer = LastLayer(self.hidden_size, 1, self.out_channels)
|
self.final_layer = LastLayer(self.hidden_size, 1, self.out_channels)
|
||||||
|
|
||||||
def prepare_input(self, x, context, y, x_shape=None):
|
def prepare_input(self, x, context, y, x_shape=None):
|
||||||
# x.shape [6, 16, 16, 16] target is [6, 16, 768, 1360]
|
# x.shape [6, 16, 16, 16] target is [6, 16, 768, 1360]
|
||||||
bs, c, h, w = x.shape
|
bs, c, h, w = x.shape
|
||||||
x = rearrange(x, 'b c (h ph) (w pw) -> b (h w) (c ph pw)', ph=2, pw=2)
|
x = rearrange(x, "b c (h ph) (w pw) -> b (h w) (c ph pw)", ph=2, pw=2)
|
||||||
x_id = torch.zeros(h // 2, w // 2, 3)
|
x_id = torch.zeros(h // 2, w // 2, 3)
|
||||||
x_id[..., 1] = x_id[..., 1] + torch.arange(h // 2)[:, None]
|
x_id[..., 1] = x_id[..., 1] + torch.arange(h // 2)[:, None]
|
||||||
x_id[..., 2] = x_id[..., 2] + torch.arange(w // 2)[None, :]
|
x_id[..., 2] = x_id[..., 2] + torch.arange(w // 2)[None, :]
|
||||||
x_ids = repeat(x_id, 'h w c -> b (h w) c', b=bs)
|
x_ids = repeat(x_id, "h w c -> b (h w) c", b=bs)
|
||||||
txt_ids = torch.zeros(bs, context.shape[1], 3)
|
txt_ids = torch.zeros(bs, context.shape[1], 3)
|
||||||
return x, x_ids.to(x), context.to(x), txt_ids.to(x), y.to(x), h, w
|
return x, x_ids.to(x), context.to(x), txt_ids.to(x), y.to(x), h, w
|
||||||
|
|
||||||
def unpack(self, x: Tensor, height: int, width: int) -> Tensor:
|
def unpack(self, x: Tensor, height: int, width: int) -> Tensor:
|
||||||
return rearrange(
|
return rearrange(
|
||||||
x,
|
x,
|
||||||
'b (h w) (c ph pw) -> b c (h ph) (w pw)',
|
"b (h w) (c ph pw) -> b c (h ph) (w pw)",
|
||||||
h=math.ceil(height / 2),
|
h=math.ceil(height/2),
|
||||||
w=math.ceil(width / 2),
|
w=math.ceil(width/2),
|
||||||
ph=2,
|
ph=2,
|
||||||
pw=2,
|
pw=2,
|
||||||
)
|
)
|
||||||
|
|
||||||
def load_pretrained_model(self, pretrained_model):
|
def merge_diffuser_lora(self, ori_sd, lora_sd, scale=1.0):
|
||||||
if next(self.parameters()).device.type == 'meta':
|
key_map = {
|
||||||
map_location = we.device_id
|
"single_blocks.{}.linear1.weight": {"key_list": [
|
||||||
else:
|
["transformer.single_transformer_blocks.{}.attn.to_q.lora_A.weight",
|
||||||
map_location = 'cpu'
|
"transformer.single_transformer_blocks.{}.attn.to_q.lora_B.weight", [0, 3072]],
|
||||||
if pretrained_model is not None:
|
["transformer.single_transformer_blocks.{}.attn.to_k.lora_A.weight",
|
||||||
with FS.get_from(pretrained_model,
|
"transformer.single_transformer_blocks.{}.attn.to_k.lora_B.weight", [3072, 6144]],
|
||||||
wait_finish=True) as local_model:
|
["transformer.single_transformer_blocks.{}.attn.to_v.lora_A.weight",
|
||||||
if local_model.endswith('safetensors'):
|
"transformer.single_transformer_blocks.{}.attn.to_v.lora_B.weight", [6144, 9216]],
|
||||||
from safetensors.torch import load_file as load_safetensors
|
["transformer.single_transformer_blocks.{}.proj_mlp.lora_A.weight",
|
||||||
sd = load_safetensors(local_model, device=map_location)
|
"transformer.single_transformer_blocks.{}.proj_mlp.lora_B.weight", [9216, 21504]]
|
||||||
|
], "num": 38},
|
||||||
|
"single_blocks.{}.modulation.lin.weight": {"key_list": [
|
||||||
|
["transformer.single_transformer_blocks.{}.norm.linear.lora_A.weight",
|
||||||
|
"transformer.single_transformer_blocks.{}.norm.linear.lora_B.weight", [0, 9216]],
|
||||||
|
], "num": 38},
|
||||||
|
"single_blocks.{}.linear2.weight": {"key_list": [
|
||||||
|
["transformer.single_transformer_blocks.{}.proj_out.lora_A.weight",
|
||||||
|
"transformer.single_transformer_blocks.{}.proj_out.lora_B.weight", [0, 3072]],
|
||||||
|
], "num": 38},
|
||||||
|
"double_blocks.{}.txt_attn.qkv.weight": {"key_list": [
|
||||||
|
["transformer.transformer_blocks.{}.attn.add_q_proj.lora_A.weight",
|
||||||
|
"transformer.transformer_blocks.{}.attn.add_q_proj.lora_B.weight", [0, 3072]],
|
||||||
|
["transformer.transformer_blocks.{}.attn.add_k_proj.lora_A.weight",
|
||||||
|
"transformer.transformer_blocks.{}.attn.add_k_proj.lora_B.weight", [3072, 6144]],
|
||||||
|
["transformer.transformer_blocks.{}.attn.add_v_proj.lora_A.weight",
|
||||||
|
"transformer.transformer_blocks.{}.attn.add_v_proj.lora_B.weight", [6144, 9216]],
|
||||||
|
], "num": 19},
|
||||||
|
"double_blocks.{}.img_attn.qkv.weight": {"key_list": [
|
||||||
|
["transformer.transformer_blocks.{}.attn.to_q.lora_A.weight",
|
||||||
|
"transformer.transformer_blocks.{}.attn.to_q.lora_B.weight", [0, 3072]],
|
||||||
|
["transformer.transformer_blocks.{}.attn.to_k.lora_A.weight",
|
||||||
|
"transformer.transformer_blocks.{}.attn.to_k.lora_B.weight", [3072, 6144]],
|
||||||
|
["transformer.transformer_blocks.{}.attn.to_v.lora_A.weight",
|
||||||
|
"transformer.transformer_blocks.{}.attn.to_v.lora_B.weight", [6144, 9216]],
|
||||||
|
], "num": 19},
|
||||||
|
"double_blocks.{}.img_attn.proj.weight": {"key_list": [
|
||||||
|
["transformer.transformer_blocks.{}.attn.to_out.0.lora_A.weight",
|
||||||
|
"transformer.transformer_blocks.{}.attn.to_out.0.lora_B.weight", [0, 3072]]
|
||||||
|
], "num": 19},
|
||||||
|
"double_blocks.{}.txt_attn.proj.weight": {"key_list": [
|
||||||
|
["transformer.transformer_blocks.{}.attn.to_add_out.lora_A.weight",
|
||||||
|
"transformer.transformer_blocks.{}.attn.to_add_out.lora_B.weight", [0, 3072]]
|
||||||
|
], "num": 19},
|
||||||
|
"double_blocks.{}.img_mlp.0.weight": {"key_list": [
|
||||||
|
["transformer.transformer_blocks.{}.ff.net.0.proj.lora_A.weight",
|
||||||
|
"transformer.transformer_blocks.{}.ff.net.0.proj.lora_B.weight", [0, 12288]]
|
||||||
|
], "num": 19},
|
||||||
|
"double_blocks.{}.img_mlp.2.weight": {"key_list": [
|
||||||
|
["transformer.transformer_blocks.{}.ff.net.2.lora_A.weight",
|
||||||
|
"transformer.transformer_blocks.{}.ff.net.2.lora_B.weight", [0, 3072]]
|
||||||
|
], "num": 19},
|
||||||
|
"double_blocks.{}.txt_mlp.0.weight": {"key_list": [
|
||||||
|
["transformer.transformer_blocks.{}.ff_context.net.0.proj.lora_A.weight",
|
||||||
|
"transformer.transformer_blocks.{}.ff_context.net.0.proj.lora_B.weight", [0, 12288]]
|
||||||
|
], "num": 19},
|
||||||
|
"double_blocks.{}.txt_mlp.2.weight": {"key_list": [
|
||||||
|
["transformer.transformer_blocks.{}.ff_context.net.2.lora_A.weight",
|
||||||
|
"transformer.transformer_blocks.{}.ff_context.net.2.lora_B.weight", [0, 3072]]
|
||||||
|
], "num": 19},
|
||||||
|
"double_blocks.{}.img_mod.lin.weight": {"key_list": [
|
||||||
|
["transformer.transformer_blocks.{}.norm1.linear.lora_A.weight",
|
||||||
|
"transformer.transformer_blocks.{}.norm1.linear.lora_B.weight", [0, 18432]]
|
||||||
|
], "num": 19},
|
||||||
|
"double_blocks.{}.txt_mod.lin.weight": {"key_list": [
|
||||||
|
["transformer.transformer_blocks.{}.norm1_context.linear.lora_A.weight",
|
||||||
|
"transformer.transformer_blocks.{}.norm1_context.linear.lora_B.weight", [0, 18432]]
|
||||||
|
], "num": 19}
|
||||||
|
}
|
||||||
|
cover_lora_keys = set()
|
||||||
|
cover_ori_keys = set()
|
||||||
|
for k, v in key_map.items():
|
||||||
|
key_list = v["key_list"]
|
||||||
|
block_num = v["num"]
|
||||||
|
for block_id in range(block_num):
|
||||||
|
for k_list in key_list:
|
||||||
|
if k_list[0].format(block_id) in lora_sd and k_list[1].format(block_id) in lora_sd:
|
||||||
|
cover_lora_keys.add(k_list[0].format(block_id))
|
||||||
|
cover_lora_keys.add(k_list[1].format(block_id))
|
||||||
|
current_weight = torch.matmul(lora_sd[k_list[0].format(block_id)].permute(1, 0),
|
||||||
|
lora_sd[k_list[1].format(block_id)].permute(1, 0)).permute(1, 0)
|
||||||
|
ori_sd[k.format(block_id)][k_list[2][0]:k_list[2][1], ...] += scale * current_weight
|
||||||
|
cover_ori_keys.add(k.format(block_id))
|
||||||
|
# lora_sd.pop(k_list[0].format(block_id))
|
||||||
|
# lora_sd.pop(k_list[1].format(block_id))
|
||||||
|
self.logger.info(f"merge_blackforest_lora loads lora'parameters lora-paras: \n"
|
||||||
|
f"cover-{len(cover_lora_keys)} vs total {len(lora_sd)} \n"
|
||||||
|
f"cover ori-{len(cover_ori_keys)} vs total {len(ori_sd)}")
|
||||||
|
return ori_sd
|
||||||
|
|
||||||
|
def merge_swift_lora(self, ori_sd, lora_sd, scale = 1.0):
|
||||||
|
have_lora_keys = {}
|
||||||
|
for k, v in lora_sd.items():
|
||||||
|
k = k[len("model."):] if k.startswith("model.") else k
|
||||||
|
ori_key = k.split("lora")[0] + "weight"
|
||||||
|
if ori_key not in ori_sd:
|
||||||
|
raise f"{ori_key} should in the original statedict"
|
||||||
|
if ori_key not in have_lora_keys:
|
||||||
|
have_lora_keys[ori_key] = {}
|
||||||
|
if "lora_A" in k:
|
||||||
|
have_lora_keys[ori_key]["lora_A"] = v
|
||||||
|
elif "lora_B" in k:
|
||||||
|
have_lora_keys[ori_key]["lora_B"] = v
|
||||||
|
else:
|
||||||
|
raise NotImplementedError
|
||||||
|
self.logger.info(f"merge_swift_lora loads lora'parameters {len(have_lora_keys)}")
|
||||||
|
for key, v in have_lora_keys.items():
|
||||||
|
current_weight = torch.matmul(v["lora_A"].permute(1, 0), v["lora_B"].permute(1, 0)).permute(1, 0)
|
||||||
|
ori_sd[key] += scale * current_weight
|
||||||
|
return ori_sd
|
||||||
|
|
||||||
|
|
||||||
|
def merge_blackforest_lora(self, ori_sd, lora_sd, scale = 1.0):
|
||||||
|
have_lora_keys = {}
|
||||||
|
cover_lora_keys = set()
|
||||||
|
cover_ori_keys = set()
|
||||||
|
for k, v in lora_sd.items():
|
||||||
|
if "lora" in k:
|
||||||
|
ori_key = k.split("lora")[0] + "weight"
|
||||||
|
if ori_key not in ori_sd:
|
||||||
|
raise f"{ori_key} should in the original statedict"
|
||||||
|
if ori_key not in have_lora_keys:
|
||||||
|
have_lora_keys[ori_key] = {}
|
||||||
|
if "lora_A" in k:
|
||||||
|
have_lora_keys[ori_key]["lora_A"] = v
|
||||||
|
cover_lora_keys.add(k)
|
||||||
|
cover_ori_keys.add(ori_key)
|
||||||
|
elif "lora_B" in k:
|
||||||
|
have_lora_keys[ori_key]["lora_B"] = v
|
||||||
|
cover_lora_keys.add(k)
|
||||||
|
cover_ori_keys.add(ori_key)
|
||||||
|
else:
|
||||||
|
if k in ori_sd:
|
||||||
|
ori_sd[k] = v
|
||||||
|
cover_lora_keys.add(k)
|
||||||
|
cover_ori_keys.add(k)
|
||||||
else:
|
else:
|
||||||
sd = torch.load(local_model, map_location=map_location)
|
print("unsurpport keys: ", k)
|
||||||
missing, unexpected = self.load_state_dict(sd,
|
self.logger.info(f"merge_blackforest_lora loads lora'parameters lora-paras: \n"
|
||||||
strict=False,
|
f"cover-{len(cover_lora_keys)} vs total {len(lora_sd)} \n"
|
||||||
assign=True)
|
f"cover ori-{len(cover_ori_keys)} vs total {len(ori_sd)}")
|
||||||
|
|
||||||
|
for key, v in have_lora_keys.items():
|
||||||
|
current_weight = torch.matmul(v["lora_A"].permute(1, 0), v["lora_B"].permute(1, 0)).permute(1, 0)
|
||||||
|
# print(key, ori_sd[key].shape, current_weight.shape)
|
||||||
|
ori_sd[key] += scale * current_weight
|
||||||
|
return ori_sd
|
||||||
|
|
||||||
|
def merge_comfyui_lora(self, ori_sd, lora_sd, scale = 1.0):
|
||||||
|
ori_key_map = {key.replace("_", ".") : key for key in ori_sd.keys()}
|
||||||
|
parse_ckpt = OrderedDict()
|
||||||
|
for k, v in lora_sd.items():
|
||||||
|
if "alpha" in k:
|
||||||
|
continue
|
||||||
|
k = k.replace("lora_unet_", "").replace("_", ".")
|
||||||
|
map_k = ori_key_map[k.split(".lora")[0] + ".weight"]
|
||||||
|
if map_k not in parse_ckpt:
|
||||||
|
parse_ckpt[map_k] = {}
|
||||||
|
if "lora.up" in k:
|
||||||
|
parse_ckpt[map_k]["lora_up"] = v
|
||||||
|
elif "lora.down" in k:
|
||||||
|
parse_ckpt[map_k]["lora_down"] = v
|
||||||
|
if self.cache_pretrain_model:
|
||||||
|
self.lora_dict[self.comfyui_lora_model] = {}
|
||||||
|
|
||||||
|
for key, v in parse_ckpt.items():
|
||||||
|
current_weight = torch.matmul(v["lora_down"].permute(1, 0), v["lora_up"].permute(1, 0)).permute(1, 0)
|
||||||
|
self.lora_dict[self.comfyui_lora_model] = current_weight
|
||||||
|
ori_sd[key] += scale * current_weight
|
||||||
|
return ori_sd
|
||||||
|
|
||||||
|
def easy_lora_merge(self, ori_sd, lora_sd, scale = 1.0):
|
||||||
|
for key, v in lora_sd.items():
|
||||||
|
ori_sd[key] += scale * v
|
||||||
|
return ori_sd
|
||||||
|
|
||||||
|
def load_pretrained_model(self, pretrained_model, lora_scale = 1.0):
|
||||||
|
if next(self.parameters()).device.type == 'meta':
|
||||||
|
map_location = torch.device(we.device_id)
|
||||||
|
safe_device = we.device_id
|
||||||
|
else:
|
||||||
|
map_location = "cpu"
|
||||||
|
safe_device = "cpu"
|
||||||
|
|
||||||
|
if pretrained_model is not None:
|
||||||
|
if not hasattr(self, "ckpt"):
|
||||||
|
with FS.get_from(pretrained_model, wait_finish=True) as local_model:
|
||||||
|
if local_model.endswith('safetensors'):
|
||||||
|
from safetensors.torch import load_file as load_safetensors
|
||||||
|
ckpt = load_safetensors(local_model, device=safe_device)
|
||||||
|
else:
|
||||||
|
ckpt = torch.load(local_model, map_location=map_location, weights_only=True)
|
||||||
|
if "state_dict" in ckpt:
|
||||||
|
ckpt = ckpt["state_dict"]
|
||||||
|
if "model" in ckpt:
|
||||||
|
ckpt = ckpt["model"]["model"]
|
||||||
|
if self.cache_pretrain_model:
|
||||||
|
self.ckpt = ckpt
|
||||||
|
self.lora_dict = {}
|
||||||
|
else:
|
||||||
|
ckpt = self.ckpt
|
||||||
|
|
||||||
|
new_ckpt = OrderedDict()
|
||||||
|
for k, v in ckpt.items():
|
||||||
|
if k in ("img_in.weight"):
|
||||||
|
model_p = self.state_dict()[k]
|
||||||
|
if v.shape != model_p.shape:
|
||||||
|
expanded_state_dict_weight = torch.zeros_like(model_p, device=v.device)
|
||||||
|
slices = tuple(slice(0, dim) for dim in v.shape)
|
||||||
|
expanded_state_dict_weight[slices] = v
|
||||||
|
new_ckpt[k] = expanded_state_dict_weight
|
||||||
|
else:
|
||||||
|
new_ckpt[k] = v
|
||||||
|
else:
|
||||||
|
new_ckpt[k] = v
|
||||||
|
|
||||||
|
|
||||||
|
if self.lora_model is not None:
|
||||||
|
with FS.get_from(self.lora_model, wait_finish=True) as local_model:
|
||||||
|
if local_model.endswith('safetensors'):
|
||||||
|
from safetensors.torch import load_file as load_safetensors
|
||||||
|
lora_sd = load_safetensors(local_model, device=safe_device)
|
||||||
|
else:
|
||||||
|
lora_sd = torch.load(local_model, map_location=map_location, weights_only=True)
|
||||||
|
new_ckpt = self.merge_diffuser_lora(new_ckpt, lora_sd, scale=lora_scale)
|
||||||
|
if self.swift_lora_model is not None:
|
||||||
|
if not isinstance(self.swift_lora_model, list):
|
||||||
|
self.swift_lora_model = [(self.swift_lora_model, 1.0)]
|
||||||
|
for lora_model in self.swift_lora_model:
|
||||||
|
if isinstance(lora_model, str):
|
||||||
|
lora_model = (lora_model, 1.0/len(self.swift_lora_model))
|
||||||
|
print(lora_model)
|
||||||
|
self.logger.info(f"load swift lora model: {lora_model}")
|
||||||
|
with FS.get_from(lora_model[0], wait_finish=True) as local_model:
|
||||||
|
if local_model.endswith('safetensors'):
|
||||||
|
from safetensors.torch import load_file as load_safetensors
|
||||||
|
lora_sd = load_safetensors(local_model, device=safe_device)
|
||||||
|
else:
|
||||||
|
lora_sd = torch.load(local_model, map_location=map_location, weights_only=True)
|
||||||
|
new_ckpt = self.merge_swift_lora(new_ckpt, lora_sd, scale=lora_model[1])
|
||||||
|
|
||||||
|
if self.blackforest_lora_model is not None:
|
||||||
|
with FS.get_from(self.blackforest_lora_model, wait_finish=True) as local_model:
|
||||||
|
if local_model.endswith('safetensors'):
|
||||||
|
from safetensors.torch import load_file as load_safetensors
|
||||||
|
lora_sd = load_safetensors(local_model, device=safe_device)
|
||||||
|
else:
|
||||||
|
lora_sd = torch.load(local_model, map_location=map_location, weights_only=True)
|
||||||
|
new_ckpt = self.merge_blackforest_lora(new_ckpt, lora_sd, scale=lora_scale)
|
||||||
|
|
||||||
|
if self.comfyui_lora_model is not None:
|
||||||
|
if hasattr(self, "current_lora") and self.current_lora == self.comfyui_lora_model:
|
||||||
|
return
|
||||||
|
if hasattr(self, "lora_dict") and self.comfyui_lora_model in self.lora_dict:
|
||||||
|
new_ckpt = self.easy_lora_merge(new_ckpt, self.lora_dict[self.comfyui_lora_model], scale=lora_scale)
|
||||||
|
else:
|
||||||
|
with FS.get_from(self.comfyui_lora_model, wait_finish=True) as local_model:
|
||||||
|
if local_model.endswith('safetensors'):
|
||||||
|
from safetensors.torch import load_file as load_safetensors
|
||||||
|
lora_sd = load_safetensors(local_model, device=safe_device)
|
||||||
|
else:
|
||||||
|
lora_sd = torch.load(local_model, map_location=map_location, weights_only=True)
|
||||||
|
new_ckpt = self.merge_comfyui_lora(new_ckpt, lora_sd, scale=lora_scale)
|
||||||
|
if self.comfyui_lora_model:
|
||||||
|
self.current_lora = self.comfyui_lora_model
|
||||||
|
|
||||||
|
|
||||||
|
adapter_ckpt = {}
|
||||||
|
if self.pretrain_adapter is not None:
|
||||||
|
with FS.get_from(self.pretrain_adapter, wait_finish=True) as local_adapter:
|
||||||
|
if local_adapter.endswith('safetensors'):
|
||||||
|
from safetensors.torch import load_file as load_safetensors
|
||||||
|
adapter_ckpt = load_safetensors(local_adapter, device=safe_device)
|
||||||
|
else:
|
||||||
|
adapter_ckpt = torch.load(local_adapter, map_location=map_location, weights_only=True)
|
||||||
|
new_ckpt.update(adapter_ckpt)
|
||||||
|
|
||||||
|
missing, unexpected = self.load_state_dict(new_ckpt, strict=False, assign=True)
|
||||||
self.logger.info(
|
self.logger.info(
|
||||||
f'Restored from {pretrained_model} with {len(missing)} missing and {len(unexpected)} unexpected keys'
|
f'Restored from {pretrained_model} with {len(missing)} missing and {len(unexpected)} unexpected keys'
|
||||||
)
|
)
|
||||||
if len(missing) > 0:
|
if len(missing) > 0:
|
||||||
self.logger.info(f'Missing Keys:\n {missing}') # noqa
|
self.logger.info(f'Missing Keys:\n {missing}')
|
||||||
if len(unexpected) > 0:
|
if len(unexpected) > 0:
|
||||||
self.logger.info(f'\nUnexpected Keys:\n {unexpected}') # noqa
|
self.logger.info(f'\nUnexpected Keys:\n {unexpected}')
|
||||||
|
|
||||||
def forward(self,
|
def forward(
|
||||||
x: Tensor,
|
self,
|
||||||
t: Tensor,
|
x: Tensor,
|
||||||
cond: dict = {},
|
t: Tensor,
|
||||||
guidance: Tensor | None = None,
|
cond: dict = {},
|
||||||
gc_seg: int = 0) -> Tensor:
|
guidance: Tensor | None = None,
|
||||||
x, x_ids, txt, txt_ids, y, h, w = self.prepare_input(
|
gc_seg: int = 0
|
||||||
x, cond['context'], cond['y'])
|
) -> Tensor:
|
||||||
|
x, x_ids, txt, txt_ids, y, h, w = self.prepare_input(x, cond["context"], cond["y"])
|
||||||
# running on sequences img
|
# running on sequences img
|
||||||
x = self.img_in(x)
|
x = self.img_in(x)
|
||||||
vec = self.time_in(timestep_embedding(t, 256))
|
vec = self.time_in(timestep_embedding(t, 256))
|
||||||
if self.guidance_embed:
|
if self.guidance_embed:
|
||||||
if guidance is None:
|
if guidance is None:
|
||||||
raise ValueError(
|
raise ValueError("Didn't get guidance strength for guidance distilled model.")
|
||||||
"Didn't get guidance strength for guidance distilled model."
|
|
||||||
)
|
|
||||||
vec = vec + self.guidance_in(timestep_embedding(guidance, 256))
|
vec = vec + self.guidance_in(timestep_embedding(guidance, 256))
|
||||||
vec = vec + self.vector_in(y)
|
vec = vec + self.vector_in(y)
|
||||||
txt = self.txt_in(txt)
|
txt = self.txt_in(txt)
|
||||||
@@ -211,12 +484,11 @@ class Flux(BaseModel):
|
|||||||
x = torch.cat((txt, x), 1)
|
x = torch.cat((txt, x), 1)
|
||||||
if self.use_grad_checkpoint and gc_seg >= 0:
|
if self.use_grad_checkpoint and gc_seg >= 0:
|
||||||
x = checkpoint_sequential(
|
x = checkpoint_sequential(
|
||||||
functions=[
|
functions=[partial(block, **kwargs) for block in self.double_blocks],
|
||||||
partial(block, **kwargs) for block in self.double_blocks
|
|
||||||
],
|
|
||||||
segments=gc_seg if gc_seg > 0 else len(self.double_blocks),
|
segments=gc_seg if gc_seg > 0 else len(self.double_blocks),
|
||||||
input=x,
|
input=x,
|
||||||
use_reentrant=False)
|
use_reentrant=False
|
||||||
|
)
|
||||||
else:
|
else:
|
||||||
for block in self.double_blocks:
|
for block in self.double_blocks:
|
||||||
x = block(x, **kwargs)
|
x = block(x, **kwargs)
|
||||||
@@ -228,18 +500,16 @@ class Flux(BaseModel):
|
|||||||
|
|
||||||
if self.use_grad_checkpoint and gc_seg >= 0:
|
if self.use_grad_checkpoint and gc_seg >= 0:
|
||||||
x = checkpoint_sequential(
|
x = checkpoint_sequential(
|
||||||
functions=[
|
functions=[partial(block, **kwargs) for block in self.single_blocks],
|
||||||
partial(block, **kwargs) for block in self.single_blocks
|
|
||||||
],
|
|
||||||
segments=gc_seg if gc_seg > 0 else len(self.single_blocks),
|
segments=gc_seg if gc_seg > 0 else len(self.single_blocks),
|
||||||
input=x,
|
input=x,
|
||||||
use_reentrant=False)
|
use_reentrant=False
|
||||||
|
)
|
||||||
else:
|
else:
|
||||||
for block in self.single_blocks:
|
for block in self.single_blocks:
|
||||||
x = block(x, **kwargs)
|
x = block(x, **kwargs)
|
||||||
x = x[:, txt.shape[1]:, ...]
|
x = x[:, txt.shape[1] :, ...]
|
||||||
x = self.final_layer(
|
x = self.final_layer(x, vec) # (N, T, patch_size ** 2 * out_channels) 6 64 64
|
||||||
x, vec) # (N, T, patch_size ** 2 * out_channels) 6 64 64
|
|
||||||
x = self.unpack(x, h, w)
|
x = self.unpack(x, h, w)
|
||||||
return x
|
return x
|
||||||
|
|
||||||
@@ -249,11 +519,13 @@ class Flux(BaseModel):
|
|||||||
__class__.__name__,
|
__class__.__name__,
|
||||||
Flux.para_dict,
|
Flux.para_dict,
|
||||||
set_name=True)
|
set_name=True)
|
||||||
|
|
||||||
@BACKBONES.register_class()
|
@BACKBONES.register_class()
|
||||||
class FluxMR(Flux):
|
class FluxMR(Flux):
|
||||||
def prepare_input(self, x, cond):
|
def prepare_input(self, x, cond):
|
||||||
context, y = cond["context"].to(x), cond["y"].to(x)
|
if isinstance(cond['context'], list):
|
||||||
|
context, y = torch.cat(cond["context"], dim=0).to(x), torch.cat(cond["y"], dim=0).to(x)
|
||||||
|
else:
|
||||||
|
context, y = cond['context'].to(x), cond['y'].to(x)
|
||||||
batch_frames, batch_frames_ids = [], []
|
batch_frames, batch_frames_ids = [], []
|
||||||
for ix, shape in zip(x, cond["x_shapes"]):
|
for ix, shape in zip(x, cond["x_shapes"]):
|
||||||
# unpack image from sequence
|
# unpack image from sequence
|
||||||
@@ -319,7 +591,7 @@ class FluxMR(Flux):
|
|||||||
x, x_ids, txt, txt_ids, y, mask_x, mask_txt, seq_length_list = self.prepare_input(x, cond)
|
x, x_ids, txt, txt_ids, y, mask_x, mask_txt, seq_length_list = self.prepare_input(x, cond)
|
||||||
# running on sequences img
|
# running on sequences img
|
||||||
vec = self.time_in(timestep_embedding(t, 256))
|
vec = self.time_in(timestep_embedding(t, 256))
|
||||||
if self.guidance_embed:
|
if self.guidance_embed and guidance[-1] >= 0:
|
||||||
if guidance is None:
|
if guidance is None:
|
||||||
raise ValueError("Didn't get guidance strength for guidance distilled model.")
|
raise ValueError("Didn't get guidance strength for guidance distilled model.")
|
||||||
vec = vec + self.guidance_in(timestep_embedding(guidance, 256))
|
vec = vec + self.guidance_in(timestep_embedding(guidance, 256))
|
||||||
@@ -371,7 +643,170 @@ class FluxMR(Flux):
|
|||||||
|
|
||||||
@staticmethod
|
@staticmethod
|
||||||
def get_config_template():
|
def get_config_template():
|
||||||
return dict_to_yaml('BACKBONE',
|
return dict_to_yaml('MODEL',
|
||||||
__class__.__name__,
|
__class__.__name__,
|
||||||
FluxMR.para_dict,
|
FluxMR.para_dict,
|
||||||
set_name=True)
|
set_name=True)
|
||||||
|
@BACKBONES.register_class()
|
||||||
|
class FluxMRFill(FluxMR):
|
||||||
|
def __init__(self, cfg, logger = None):
|
||||||
|
super().__init__(cfg, logger)
|
||||||
|
def prepare_input(self, x, cond):
|
||||||
|
context, y = cond["context"], cond["y"]
|
||||||
|
batch_frames, batch_frames_ids = [], []
|
||||||
|
for ix, shape, imask, ie, ie_mask in zip(x, cond["x_shapes"], cond["x_mask"],
|
||||||
|
cond["edit"], cond["edit_mask"]):
|
||||||
|
# unpack image from sequence
|
||||||
|
ix = ix[:, :shape[0] * shape[1]].view(-1, shape[0], shape[1])
|
||||||
|
imask = torch.ones_like(ix[[0], :, :]) if imask is None else imask.squeeze(0)
|
||||||
|
if len(ie) > 0:
|
||||||
|
ie = ie[0].squeeze(0)
|
||||||
|
ie_mask = torch.ones((ix.shape[0] * 4, ix.shape[1], ix.shape[2])) if ie_mask is None else ie_mask[0].squeeze(0)
|
||||||
|
else:
|
||||||
|
ie, ie_mask = torch.zeros_like(ix).to(x), torch.ones_like(imask).to(x)
|
||||||
|
ix = torch.cat([ix, ie, ie_mask], dim=0)
|
||||||
|
c, h, w = ix.shape
|
||||||
|
ix = rearrange(ix, "c (h ph) (w pw) -> (h w) (c ph pw)", ph=2, pw=2)
|
||||||
|
ix_id = torch.zeros(h // 2, w // 2, 3)
|
||||||
|
ix_id[..., 1] = ix_id[..., 1] + torch.arange(h // 2)[:, None]
|
||||||
|
ix_id[..., 2] = ix_id[..., 2] + torch.arange(w // 2)[None, :]
|
||||||
|
ix_id = rearrange(ix_id, "h w c -> (h w) c")
|
||||||
|
batch_frames.append([ix])
|
||||||
|
batch_frames_ids.append([ix_id])
|
||||||
|
x_list, x_id_list, mask_x_list, x_seq_length = [], [], [], []
|
||||||
|
for frames, frame_ids in zip(batch_frames, batch_frames_ids):
|
||||||
|
proj_frames = []
|
||||||
|
for idx, one_frame in enumerate(frames):
|
||||||
|
one_frame = self.img_in(one_frame)
|
||||||
|
proj_frames.append(one_frame)
|
||||||
|
ix = torch.cat(proj_frames, dim=0)
|
||||||
|
if_id = torch.cat(frame_ids, dim=0)
|
||||||
|
x_list.append(ix)
|
||||||
|
x_id_list.append(if_id)
|
||||||
|
mask_x_list.append(torch.ones(ix.shape[0]).to(ix.device, non_blocking=True).bool())
|
||||||
|
x_seq_length.append(ix.shape[0])
|
||||||
|
# if len(x_list) < 1: import pdb;pdb.set_trace()
|
||||||
|
x = pad_sequence(tuple(x_list), batch_first=True)
|
||||||
|
x_ids = pad_sequence(tuple(x_id_list), batch_first=True).to(x) # [b,pad_seq,2] pad (0.,0.) at dim2
|
||||||
|
mask_x = pad_sequence(tuple(mask_x_list), batch_first=True)
|
||||||
|
# import pdb;pdb.set_trace()
|
||||||
|
if isinstance(context, list):
|
||||||
|
txt_list, mask_txt_list, y_list = [], [], []
|
||||||
|
for sample_id, (ctx, yy) in enumerate(zip(context, y)):
|
||||||
|
txt_list.append(self.txt_in(ctx.to(x)))
|
||||||
|
mask_txt_list.append(torch.ones(txt_list[-1].shape[0]).to(ctx.device, non_blocking=True).bool())
|
||||||
|
y_list.append(yy.to(x))
|
||||||
|
txt = pad_sequence(tuple(txt_list), batch_first=True)
|
||||||
|
txt_ids = torch.zeros(txt.shape[0], txt.shape[1], 3).to(x)
|
||||||
|
mask_txt = pad_sequence(tuple(mask_txt_list), batch_first=True)
|
||||||
|
y = torch.cat(y_list, dim=0)
|
||||||
|
assert y.ndim == 2 and txt.ndim == 3
|
||||||
|
else:
|
||||||
|
txt = self.txt_in(context)
|
||||||
|
txt_ids = torch.zeros(context.shape[0], context.shape[1], 3).to(x)
|
||||||
|
mask_txt = torch.ones(context.shape[0], context.shape[1]).to(x.device, non_blocking=True).bool()
|
||||||
|
return x, x_ids, txt, txt_ids, y, mask_x, mask_txt, x_seq_length
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def get_config_template():
|
||||||
|
return dict_to_yaml('MODEL',
|
||||||
|
__class__.__name__,
|
||||||
|
FluxMRFill.para_dict,
|
||||||
|
set_name=True)
|
||||||
|
@BACKBONES.register_class()
|
||||||
|
class FluxMRRedux(FluxMR):
|
||||||
|
'''
|
||||||
|
ref_image_siglip + projector
|
||||||
|
'''
|
||||||
|
def __init__(self, cfg, logger = None):
|
||||||
|
super().__init__(cfg, logger)
|
||||||
|
self.redux_dim = cfg.get("REDUX_DIM", 1152)
|
||||||
|
self.context_in_dim = cfg.CONTEXT_IN_DIM
|
||||||
|
self.redux_up = nn.Linear(self.redux_dim, self.context_in_dim * 3)
|
||||||
|
self.redux_down = nn.Linear(self.context_in_dim * 3, self.context_in_dim)
|
||||||
|
|
||||||
|
|
||||||
|
def prepare_input(self, x, cond):
|
||||||
|
ref_x = cond.get("ref_x", None)
|
||||||
|
context, y = torch.cat(cond["context"], dim=0).to(x), torch.cat(cond["y"], dim=0).to(x)
|
||||||
|
if ref_x is not None:
|
||||||
|
ref_x = [torch.cat(ref_ix, dim=0).mean(dim=0, keepdim=True) for ref_ix in ref_x]
|
||||||
|
ref_x = self.redux_down(nn.functional.silu(self.redux_up(torch.cat(ref_x, dim=0))))
|
||||||
|
context = torch.cat((context, ref_x), dim=-2)
|
||||||
|
|
||||||
|
batch_frames, batch_frames_ids = [], []
|
||||||
|
for ix, shape in zip(x, cond["x_shapes"]):
|
||||||
|
# unpack image from sequence
|
||||||
|
ix = ix[:, :shape[0] * shape[1]].view(-1, shape[0], shape[1])
|
||||||
|
c, h, w = ix.shape
|
||||||
|
ix = rearrange(ix, "c (h ph) (w pw) -> (h w) (c ph pw)", ph=2, pw=2)
|
||||||
|
ix_id = torch.zeros(h // 2, w // 2, 3)
|
||||||
|
ix_id[..., 1] = ix_id[..., 1] + torch.arange(h // 2)[:, None]
|
||||||
|
ix_id[..., 2] = ix_id[..., 2] + torch.arange(w // 2)[None, :]
|
||||||
|
ix_id = rearrange(ix_id, "h w c -> (h w) c")
|
||||||
|
batch_frames.append([ix])
|
||||||
|
batch_frames_ids.append([ix_id])
|
||||||
|
|
||||||
|
x_list, x_id_list, mask_x_list, x_seq_length = [], [], [], []
|
||||||
|
for frames, frame_ids in zip(batch_frames, batch_frames_ids):
|
||||||
|
proj_frames = []
|
||||||
|
for idx, one_frame in enumerate(frames):
|
||||||
|
one_frame = self.img_in(one_frame)
|
||||||
|
proj_frames.append(one_frame)
|
||||||
|
ix = torch.cat(proj_frames, dim=0)
|
||||||
|
if_id = torch.cat(frame_ids, dim=0)
|
||||||
|
x_list.append(ix)
|
||||||
|
x_id_list.append(if_id)
|
||||||
|
mask_x_list.append(torch.ones(ix.shape[0]).to(ix.device, non_blocking=True).bool())
|
||||||
|
x_seq_length.append(ix.shape[0])
|
||||||
|
x = pad_sequence(tuple(x_list), batch_first=True)
|
||||||
|
x_ids = pad_sequence(tuple(x_id_list), batch_first=True).to(x) # [b,pad_seq,2] pad (0.,0.) at dim2
|
||||||
|
mask_x = pad_sequence(tuple(mask_x_list), batch_first=True)
|
||||||
|
|
||||||
|
txt = self.txt_in(context)
|
||||||
|
txt_ids = torch.zeros(context.shape[0], context.shape[1], 3).to(x)
|
||||||
|
mask_txt = torch.ones(context.shape[0], context.shape[1]).to(x.device, non_blocking=True).bool()
|
||||||
|
|
||||||
|
return x, x_ids, txt, txt_ids, y, mask_x, mask_txt, x_seq_length
|
||||||
|
@staticmethod
|
||||||
|
def get_config_template():
|
||||||
|
return dict_to_yaml('MODEL',
|
||||||
|
__class__.__name__,
|
||||||
|
FluxMRRedux.para_dict,
|
||||||
|
set_name=True)
|
||||||
|
@BACKBONES.register_class()
|
||||||
|
class FluxMRControl(FluxMR):
|
||||||
|
'''
|
||||||
|
cat([x, ie]) ensure the same size bettwn the x and ie
|
||||||
|
'''
|
||||||
|
def prepare_input(self, x, cond, *args, **kwargs ):
|
||||||
|
context, y = torch.cat(cond["context"], dim=0).to(x), torch.cat(cond["y"], dim=0).to(x)
|
||||||
|
x_list, x_id_list, mask_x_list, x_seq_length = [], [], [], []
|
||||||
|
for ix, shape, ie in zip(x, cond["x_shapes"], cond["edit"]):
|
||||||
|
ix = ix[:, :shape[0] * shape[1]].view(-1, shape[0], shape[1])
|
||||||
|
ix = torch.cat([ix, ie], dim=0)
|
||||||
|
c, h, w = ix.shape
|
||||||
|
ix = rearrange(ix, "c (h ph) (w pw) -> (h w) (c ph pw)", ph=2, pw=2)
|
||||||
|
ix_id = torch.zeros(h // 2, w // 2, 3)
|
||||||
|
ix_id[..., 1] = ix_id[..., 1] + torch.arange(h // 2)[:, None]
|
||||||
|
ix_id[..., 2] = ix_id[..., 2] + torch.arange(w // 2)[None, :]
|
||||||
|
ix_id = rearrange(ix_id, "h w c -> (h w) c")
|
||||||
|
x_list.append(self.img_in(ix))
|
||||||
|
x_id_list.append(ix_id)
|
||||||
|
mask_x_list.append(torch.ones(ix.shape[0]).to(ix.device, non_blocking=True).bool())
|
||||||
|
x_seq_length.append(ix.shape[0])
|
||||||
|
# if len(x_list) < 1: import pdb;pdb.set_trace()
|
||||||
|
x = pad_sequence(tuple(x_list), batch_first=True)
|
||||||
|
x_ids = pad_sequence(tuple(x_id_list), batch_first=True).to(x) # [b,pad_seq,2] pad (0.,0.) at dim2
|
||||||
|
mask_x = pad_sequence(tuple(mask_x_list), batch_first=True)
|
||||||
|
txt = self.txt_in(context)
|
||||||
|
txt_ids = torch.zeros(context.shape[0], context.shape[1], 3).to(x)
|
||||||
|
mask_txt = torch.ones(context.shape[0], context.shape[1]).to(x.device, non_blocking=True).bool()
|
||||||
|
return x, x_ids, txt, txt_ids, y, mask_x, mask_txt, x_seq_length
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def get_config_template():
|
||||||
|
return dict_to_yaml('MODEL',
|
||||||
|
__class__.__name__,
|
||||||
|
FluxMRControl.para_dict,
|
||||||
|
set_name=True)
|
||||||
|
|||||||
@@ -1,5 +1,7 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
# This file contains code that is adapted from
|
||||||
|
# https://github.com/black-forest-labs/flux.git
|
||||||
from __future__ import annotations
|
from __future__ import annotations
|
||||||
|
|
||||||
import math
|
import math
|
||||||
@@ -351,7 +353,7 @@ class SingleStreamBlock(nn.Module):
|
|||||||
if mask is not None:
|
if mask is not None:
|
||||||
mask = repeat(mask, 'B L S-> B H L S', H=self.num_heads)
|
mask = repeat(mask, 'B L S-> B H L S', H=self.num_heads)
|
||||||
# compute attention
|
# compute attention
|
||||||
attn = attention(q, k, v, pe=pe, mask=mask)
|
attn = attention(q, k, v, pe=pe, mask=mask, backend=self.backend)
|
||||||
# compute activation in mlp stream, cat again and run second linear layer
|
# compute activation in mlp stream, cat again and run second linear layer
|
||||||
output = self.linear2(torch.cat((attn, self.mlp_act(mlp)), 2))
|
output = self.linear2(torch.cat((attn, self.mlp_act(mlp)), 2))
|
||||||
return x + mod.gate * output
|
return x + mod.gate * output
|
||||||
|
|||||||
@@ -74,7 +74,7 @@ class VisualTransformer(BaseModel):
|
|||||||
with FS.get_from(self.pretrain_path,
|
with FS.get_from(self.pretrain_path,
|
||||||
wait_finish=True) as local_file:
|
wait_finish=True) as local_file:
|
||||||
logger.info(f'Loading checkpoint from {self.pretrain_path}')
|
logger.info(f'Loading checkpoint from {self.pretrain_path}')
|
||||||
visual_pre = torch.load(local_file, map_location='cpu')
|
visual_pre = torch.load(local_file, map_location='cpu', weights_only=True)
|
||||||
if not use_proj:
|
if not use_proj:
|
||||||
visual_pre.pop('proj')
|
visual_pre.pop('proj')
|
||||||
if visual_pre['conv1.weight'].dtype == torch.float16:
|
if visual_pre['conv1.weight'].dtype == torch.float16:
|
||||||
@@ -145,7 +145,7 @@ class SomeFTVisualTransformer(BaseModel):
|
|||||||
with FS.get_from(self.pretrain_path,
|
with FS.get_from(self.pretrain_path,
|
||||||
wait_finish=True) as local_file:
|
wait_finish=True) as local_file:
|
||||||
logger.info(f'Loading checkpoint from {self.pretrain_path}')
|
logger.info(f'Loading checkpoint from {self.pretrain_path}')
|
||||||
visual_pre = torch.load(local_file, map_location='cpu')
|
visual_pre = torch.load(local_file, map_location='cpu', weights_only=True)
|
||||||
state_dict_update = self.reformat_state_dict(visual_pre)
|
state_dict_update = self.reformat_state_dict(visual_pre)
|
||||||
self.visual.load_state_dict(state_dict_update, strict=True)
|
self.visual.load_state_dict(state_dict_update, strict=True)
|
||||||
|
|
||||||
|
|||||||
@@ -1136,7 +1136,7 @@ class MMDiT(BaseModel):
|
|||||||
from safetensors.torch import load_file as load_safetensors
|
from safetensors.torch import load_file as load_safetensors
|
||||||
model = load_safetensors(local_path)
|
model = load_safetensors(local_path)
|
||||||
else:
|
else:
|
||||||
model = torch.load(local_path, map_location='cpu')
|
model = torch.load(local_path, map_location='cpu', weights_only=True)
|
||||||
if 'state_dict' in model:
|
if 'state_dict' in model:
|
||||||
model = model['state_dict']
|
model = model['state_dict']
|
||||||
new_ckpt = OrderedDict()
|
new_ckpt = OrderedDict()
|
||||||
|
|||||||
@@ -354,7 +354,7 @@ class PixArt(BaseModel):
|
|||||||
def load_pretrained_model(self, pretrained_model):
|
def load_pretrained_model(self, pretrained_model):
|
||||||
if pretrained_model:
|
if pretrained_model:
|
||||||
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
||||||
model = torch.load(local_path, map_location='cpu')
|
model = torch.load(local_path, map_location='cpu', weights_only=True)
|
||||||
if 'state_dict' in model:
|
if 'state_dict' in model:
|
||||||
model = model['state_dict']
|
model = model['state_dict']
|
||||||
new_ckpt = OrderedDict()
|
new_ckpt = OrderedDict()
|
||||||
|
|||||||
@@ -0,0 +1,2 @@
|
|||||||
|
# -*- coding: utf-8 -*-
|
||||||
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
|||||||
@@ -10,7 +10,7 @@ import warnings
|
|||||||
|
|
||||||
import torch
|
import torch
|
||||||
import torch.nn as nn
|
import torch.nn as nn
|
||||||
from torch.cuda import amp
|
from torch import amp
|
||||||
from torch.nn import functional as F
|
from torch.nn import functional as F
|
||||||
from torch.nn.utils.rnn import pad_sequence
|
from torch.nn.utils.rnn import pad_sequence
|
||||||
from tqdm import tqdm
|
from tqdm import tqdm
|
||||||
@@ -440,7 +440,7 @@ def multi_head_varlen_attention(q_img,
|
|||||||
k = k.type(flash_dtype)
|
k = k.type(flash_dtype)
|
||||||
v = v.type(flash_dtype)
|
v = v.type(flash_dtype)
|
||||||
|
|
||||||
with amp.autocast():
|
with amp.autocast("cuda"):
|
||||||
x = flash_attn_varlen_func(q=q,
|
x = flash_attn_varlen_func(q=q,
|
||||||
k=k,
|
k=k,
|
||||||
v=v,
|
v=v,
|
||||||
|
|||||||
@@ -13,7 +13,7 @@ import torch.nn as nn
|
|||||||
import torch.nn.functional as F
|
import torch.nn.functional as F
|
||||||
from einops import rearrange
|
from einops import rearrange
|
||||||
from torch import Tensor
|
from torch import Tensor
|
||||||
from torch.cuda import amp
|
from torch import amp
|
||||||
from torch.nn.utils.rnn import pad_sequence
|
from torch.nn.utils.rnn import pad_sequence
|
||||||
|
|
||||||
|
|
||||||
@@ -175,7 +175,7 @@ def frame_unpad(x, shapes):
|
|||||||
return torch.concat(frames)
|
return torch.concat(frames)
|
||||||
|
|
||||||
|
|
||||||
@amp.autocast(enabled=False)
|
@amp.autocast("cuda", enabled=False)
|
||||||
def rope_params(max_seq_len, dim, theta=10000):
|
def rope_params(max_seq_len, dim, theta=10000):
|
||||||
"""
|
"""
|
||||||
Precompute the frequency tensor for complex exponentials.
|
Precompute the frequency tensor for complex exponentials.
|
||||||
@@ -189,7 +189,7 @@ def rope_params(max_seq_len, dim, theta=10000):
|
|||||||
return freqs
|
return freqs
|
||||||
|
|
||||||
|
|
||||||
@amp.autocast(enabled=False)
|
@amp.autocast("cuda", enabled=False)
|
||||||
def rope_apply(x, grid_sizes, freqs):
|
def rope_apply(x, grid_sizes, freqs):
|
||||||
"""
|
"""
|
||||||
x: [B, L, N, C].
|
x: [B, L, N, C].
|
||||||
@@ -225,7 +225,7 @@ def rope_apply(x, grid_sizes, freqs):
|
|||||||
return torch.stack(output)
|
return torch.stack(output)
|
||||||
|
|
||||||
|
|
||||||
@amp.autocast(enabled=False)
|
@amp.autocast("cuda", enabled=False)
|
||||||
def rope_apply_multires_pad(x, x_lens, x_shapes, freqs, pad=True):
|
def rope_apply_multires_pad(x, x_lens, x_shapes, freqs, pad=True):
|
||||||
"""
|
"""
|
||||||
x: [B, L, N, C].
|
x: [B, L, N, C].
|
||||||
@@ -267,7 +267,7 @@ def rope_apply_multires_pad(x, x_lens, x_shapes, freqs, pad=True):
|
|||||||
return torch.stack(output) if pad else torch.concat(output)
|
return torch.stack(output) if pad else torch.concat(output)
|
||||||
|
|
||||||
|
|
||||||
@amp.autocast(enabled=False)
|
@amp.autocast("cuda", enabled=False)
|
||||||
def rope_apply_multires(x, x_lens, x_shapes, freqs, pad=True):
|
def rope_apply_multires(x, x_lens, x_shapes, freqs, pad=True):
|
||||||
"""
|
"""
|
||||||
x: [B*L, N, C].
|
x: [B*L, N, C].
|
||||||
|
|||||||
@@ -459,7 +459,7 @@ class DiffusionUNet(BaseModel):
|
|||||||
from safetensors.torch import load_file as load_safetensors
|
from safetensors.torch import load_file as load_safetensors
|
||||||
sd = load_safetensors(path)
|
sd = load_safetensors(path)
|
||||||
else:
|
else:
|
||||||
sd = torch.load(path, map_location='cpu')
|
sd = torch.load(path, map_location='cpu', weights_only=True)
|
||||||
|
|
||||||
new_sd = OrderedDict()
|
new_sd = OrderedDict()
|
||||||
for k, v in sd.items():
|
for k, v in sd.items():
|
||||||
@@ -1231,7 +1231,7 @@ class LargenUNetXL(DiffusionUNetXL):
|
|||||||
from safetensors.torch import load_file as load_safetensors
|
from safetensors.torch import load_file as load_safetensors
|
||||||
sd = load_safetensors(path)
|
sd = load_safetensors(path)
|
||||||
else:
|
else:
|
||||||
sd = torch.load(path, map_location='cpu')
|
sd = torch.load(path, map_location='cpu', weights_only=True)
|
||||||
|
|
||||||
new_sd = OrderedDict()
|
new_sd = OrderedDict()
|
||||||
for k, v in sd.items():
|
for k, v in sd.items():
|
||||||
|
|||||||
@@ -1,7 +1,27 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
from typing import TYPE_CHECKING
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
from .diffusions import BaseDiffusion, DiffusionFluxRF
|
|
||||||
from .samplers import BaseDiffusionSampler, DDIMSampler, FlowEluerSampler
|
if TYPE_CHECKING:
|
||||||
from .schedules import (BaseNoiseScheduler, FlowMatchShiftScheduler,
|
from .diffusions import BaseDiffusion, DiffusionFluxRF
|
||||||
ScaledLinearScheduler)
|
from .samplers import BaseDiffusionSampler, DDIMSampler, FlowEluerSampler
|
||||||
|
from .schedules import (BaseNoiseScheduler, FlowMatchShiftScheduler,
|
||||||
|
ScaledLinearScheduler)
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'diffusions': ['BaseDiffusion', 'DiffusionFluxRF'],
|
||||||
|
'samplers': ['BaseDiffusionSampler', 'DDIMSampler', 'FlowEluerSampler'],
|
||||||
|
'schedules': ['BaseNoiseScheduler', 'FlowMatchShiftScheduler',
|
||||||
|
'ScaledLinearScheduler']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -34,6 +34,7 @@ class BaseDiffusion(object):
|
|||||||
|
|
||||||
def init_params(self):
|
def init_params(self):
|
||||||
self.prediction_type = self.cfg.get('PREDICTION_TYPE', 'eps')
|
self.prediction_type = self.cfg.get('PREDICTION_TYPE', 'eps')
|
||||||
|
self.use_dynamic_cfg = self.cfg.get('USE_DYNAMIC_CFG', False)
|
||||||
self.noise_scheduler = NOISE_SCHEDULERS.build(self.cfg.NOISE_SCHEDULER,
|
self.noise_scheduler = NOISE_SCHEDULERS.build(self.cfg.NOISE_SCHEDULER,
|
||||||
logger=self.logger)
|
logger=self.logger)
|
||||||
self.sampler_scheduler = NOISE_SCHEDULERS.build(self.cfg.get(
|
self.sampler_scheduler = NOISE_SCHEDULERS.build(self.cfg.get(
|
||||||
@@ -56,7 +57,6 @@ class BaseDiffusion(object):
|
|||||||
model_kwargs={},
|
model_kwargs={},
|
||||||
steps=20,
|
steps=20,
|
||||||
sampler=None,
|
sampler=None,
|
||||||
use_dynamic_cfg=False,
|
|
||||||
guide_scale=None,
|
guide_scale=None,
|
||||||
guide_rescale=None,
|
guide_rescale=None,
|
||||||
show_progress=False,
|
show_progress=False,
|
||||||
@@ -79,7 +79,7 @@ class BaseDiffusion(object):
|
|||||||
if guide_scale is None or guide_scale == 1.0:
|
if guide_scale is None or guide_scale == 1.0:
|
||||||
out = model(x=x_t, t=t, **model_kwargs)
|
out = model(x=x_t, t=t, **model_kwargs)
|
||||||
else:
|
else:
|
||||||
if use_dynamic_cfg:
|
if self.use_dynamic_cfg:
|
||||||
guidance_scale = 1 + guide_scale * (
|
guidance_scale = 1 + guide_scale * (
|
||||||
(1 - math.cos(math.pi * (
|
(1 - math.cos(math.pi * (
|
||||||
(steps - timestamp.item()) / steps)**5.0)) / 2)
|
(steps - timestamp.item()) / steps)**5.0)) / 2)
|
||||||
@@ -158,14 +158,16 @@ class BaseDiffusion(object):
|
|||||||
|
|
||||||
def get_sampler(self, sampler):
|
def get_sampler(self, sampler):
|
||||||
if isinstance(sampler, str):
|
if isinstance(sampler, str):
|
||||||
if sampler not in DIFFUSION_SAMPLERS.class_map:
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
if (not LazyImportModule.get_module_type(('DIFFUSION_SAMPLERS', sampler))) and (
|
||||||
|
sampler not in DIFFUSION_SAMPLERS.class_map):
|
||||||
if self.logger is not None:
|
if self.logger is not None:
|
||||||
self.logger.info(
|
self.logger.info(
|
||||||
f'{sampler} not in the defined samplers list {DIFFUSION_SAMPLERS.class_map.keys()}'
|
f'{sampler} not in the defined samplers list.'
|
||||||
)
|
)
|
||||||
else:
|
else:
|
||||||
print(
|
print(
|
||||||
f'{sampler} not in the defined samplers list {DIFFUSION_SAMPLERS.class_map.keys()}'
|
f'{sampler} not in the defined samplers list.'
|
||||||
)
|
)
|
||||||
return None
|
return None
|
||||||
sampler_cfg = Config(cfg_dict={'NAME': sampler}, load=False)
|
sampler_cfg = Config(cfg_dict={'NAME': sampler}, load=False)
|
||||||
|
|||||||
@@ -1,6 +1,7 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
import math
|
import math
|
||||||
|
import random
|
||||||
from dataclasses import dataclass, field
|
from dataclasses import dataclass, field
|
||||||
from typing import Callable
|
from typing import Callable
|
||||||
|
|
||||||
@@ -30,7 +31,7 @@ class ScheduleOutput(object):
|
|||||||
|
|
||||||
@NOISE_SCHEDULERS.register_class()
|
@NOISE_SCHEDULERS.register_class()
|
||||||
class BaseNoiseScheduler(object):
|
class BaseNoiseScheduler(object):
|
||||||
'''
|
r'''
|
||||||
In the diffusion model, the parameters related to the noise schedule are alpha, beta,
|
In the diffusion model, the parameters related to the noise schedule are alpha, beta,
|
||||||
and sigma. The following are the definitions of the above three parameters, which should
|
and sigma. The following are the definitions of the above three parameters, which should
|
||||||
be the basic property for the instance of noise scheduler.
|
be the basic property for the instance of noise scheduler.
|
||||||
@@ -483,6 +484,14 @@ class FlowMatchFluxShiftScheduler(FlowMatchUniformScheduler):
|
|||||||
'MAX_SHIFT': {
|
'MAX_SHIFT': {
|
||||||
'value': 1.15,
|
'value': 1.15,
|
||||||
'description': 'The max shift factor for the timestamp.'
|
'description': 'The max shift factor for the timestamp.'
|
||||||
|
},
|
||||||
|
'PRE_T_SAMPLE': {
|
||||||
|
'value': False,
|
||||||
|
'description': 'Use pre-sampled timesteps or not, default is False.'
|
||||||
|
},
|
||||||
|
'PRE_T_SAMPLE_FOLD': {
|
||||||
|
'value': 1,
|
||||||
|
'description': 'The folds of pre-sampled timesteps.'
|
||||||
}
|
}
|
||||||
}
|
}
|
||||||
|
|
||||||
@@ -492,6 +501,23 @@ class FlowMatchFluxShiftScheduler(FlowMatchUniformScheduler):
|
|||||||
self.sigmoid_scale = self.cfg.get('SIGMOID_SCALE', 1)
|
self.sigmoid_scale = self.cfg.get('SIGMOID_SCALE', 1)
|
||||||
self.base_shift = self.cfg.get('BASE_SHIFT', 0.5)
|
self.base_shift = self.cfg.get('BASE_SHIFT', 0.5)
|
||||||
self.max_shift = self.cfg.get('MAX_SHIFT', 1.15)
|
self.max_shift = self.cfg.get('MAX_SHIFT', 1.15)
|
||||||
|
self.pre_t_sample = self.cfg.get('PRE_T_SAMPLE', False)
|
||||||
|
self.pre_t_sample_fold = self.cfg.get('PRE_T_SAMPLE_FOLD', 1)
|
||||||
|
if self.pre_t_sample:
|
||||||
|
t = torch.sigmoid(torch.randn((self.num_timesteps * self.pre_t_sample_fold,)))
|
||||||
|
# Scale and reverse the values to go from 1000 to 0
|
||||||
|
timesteps = ((1 - t) * 1000)
|
||||||
|
# Sort the timesteps in descending order
|
||||||
|
self.pre_sample_timesteps, _ = torch.sort(timesteps, descending=True)
|
||||||
|
else:
|
||||||
|
self.pre_sample_timesteps = None
|
||||||
|
|
||||||
|
@property
|
||||||
|
def pre_timesteps(self):
|
||||||
|
fold_id = random.randint(0, self.pre_t_sample_fold - 1)
|
||||||
|
# print("fold_id", fold_id)
|
||||||
|
return self.pre_sample_timesteps[fold_id::self.pre_t_sample_fold]
|
||||||
|
|
||||||
|
|
||||||
def time_shift(self, mu: float, sigma_scale: float, t: Tensor):
|
def time_shift(self, mu: float, sigma_scale: float, t: Tensor):
|
||||||
return math.exp(mu) / (math.exp(mu) + (1 / t - 1)**sigma_scale)
|
return math.exp(mu) / (math.exp(mu) + (1 / t - 1)**sigma_scale)
|
||||||
@@ -516,11 +542,22 @@ class FlowMatchFluxShiftScheduler(FlowMatchUniformScheduler):
|
|||||||
n, _, h, w = x_0.shape
|
n, _, h, w = x_0.shape
|
||||||
seq_len = (h // 2 * w // 2)
|
seq_len = (h // 2 * w // 2)
|
||||||
if t is None:
|
if t is None:
|
||||||
logits_norm = torch.randn(x_0.shape[0], device=x_0.device)
|
if self.pre_t_sample:
|
||||||
logits_norm = logits_norm * self.sigmoid_scale # larger scale for more uniform sampling
|
timestep_indices = torch.randint(
|
||||||
t = logits_norm.sigmoid() * self.num_timesteps
|
1,
|
||||||
|
self.num_timesteps - 1,
|
||||||
|
(x_0.shape[0],)
|
||||||
|
)
|
||||||
|
timestep_indices = timestep_indices.long()
|
||||||
|
t = [self.pre_timesteps[x.item()].to(x_0.device) for x in timestep_indices]
|
||||||
|
t = torch.stack(t, dim=0)
|
||||||
|
else:
|
||||||
|
logits_norm = torch.randn(x_0.shape[0], device=x_0.device)
|
||||||
|
logits_norm = logits_norm * self.sigmoid_scale # larger scale for more uniform sampling
|
||||||
|
t = logits_norm.sigmoid() * self.num_timesteps
|
||||||
sigma = self.t_to_sigma(t, seq_len=seq_len)
|
sigma = self.t_to_sigma(t, seq_len=seq_len)
|
||||||
shape = (x_0.size(0), ) + (1, ) * (x_0.ndim - 1)
|
shape = (x_0.size(0), ) + (1, ) * (x_0.ndim - 1)
|
||||||
|
# print(sigma)
|
||||||
x_t = (1 - sigma.view(shape)) * x_0 + sigma.view(shape) * noise
|
x_t = (1 - sigma.view(shape)) * x_0 + sigma.view(shape) * noise
|
||||||
return ScheduleOutput(x_0=x_0,
|
return ScheduleOutput(x_0=x_0,
|
||||||
x_t=x_t,
|
x_t=x_t,
|
||||||
|
|||||||
@@ -1,8 +1,30 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
from typing import TYPE_CHECKING
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
from scepter.modules.model.embedder.embedder import (
|
|
||||||
ConcatTimestepEmbedderND, FrozenCLIPEmbedder, FrozenCLIPEmbedder2,
|
if TYPE_CHECKING:
|
||||||
FrozenOpenCLIPEmbedder, FrozenOpenCLIPEmbedder2, GeneralConditioner,
|
from scepter.modules.model.embedder.embedder import (
|
||||||
IPAdapterPlusEmbedder, RefCrossEmbedder, SD3TextEmbedder, T5EmbedderHF)
|
ConcatTimestepEmbedderND, FrozenCLIPEmbedder, FrozenCLIPEmbedder2,
|
||||||
from scepter.modules.model.embedder.flux_embedder import HFEmbedder
|
FrozenOpenCLIPEmbedder, FrozenOpenCLIPEmbedder2, GeneralConditioner,
|
||||||
|
IPAdapterPlusEmbedder, RefCrossEmbedder, SD3TextEmbedder, T5EmbedderHF)
|
||||||
|
from scepter.modules.model.embedder.flux_embedder import HFEmbedder
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'embedder': ['ConcatTimestepEmbedderND', 'FrozenCLIPEmbedder',
|
||||||
|
'FrozenCLIPEmbedder2', 'FrozenOpenCLIPEmbedder',
|
||||||
|
'FrozenOpenCLIPEmbedder2', 'GeneralConditioner',
|
||||||
|
'IPAdapterPlusEmbedder', 'RefCrossEmbedder',
|
||||||
|
'SD3TextEmbedder', 'T5EmbedderHF'],
|
||||||
|
'flux_embedder': ['HFEmbedder']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -36,7 +36,8 @@ except Exception as e:
|
|||||||
|
|
||||||
def autocast(f, enabled=True):
|
def autocast(f, enabled=True):
|
||||||
def do_autocast(*args, **kwargs):
|
def do_autocast(*args, **kwargs):
|
||||||
with torch.cuda.amp.autocast(
|
with torch.amp.autocast(
|
||||||
|
"cuda",
|
||||||
enabled=enabled,
|
enabled=enabled,
|
||||||
dtype=torch.get_autocast_gpu_dtype(),
|
dtype=torch.get_autocast_gpu_dtype(),
|
||||||
cache_enabled=torch.is_autocast_cache_enabled(),
|
cache_enabled=torch.is_autocast_cache_enabled(),
|
||||||
@@ -239,7 +240,7 @@ class FrozenOpenCLIPEmbedder(BaseEmbedder):
|
|||||||
if cfg.PRETRAINED_MODEL is not None:
|
if cfg.PRETRAINED_MODEL is not None:
|
||||||
with FS.get_from(cfg.PRETRAINED_MODEL,
|
with FS.get_from(cfg.PRETRAINED_MODEL,
|
||||||
wait_finish=True) as local_path:
|
wait_finish=True) as local_path:
|
||||||
model.load_state_dict(torch.load(local_path), strict=False)
|
model.load_state_dict(torch.load(local_path, weights_only=True), strict=False)
|
||||||
self.model = model
|
self.model = model
|
||||||
|
|
||||||
self.use_grad = cfg.get('USE_GRAD', False)
|
self.use_grad = cfg.get('USE_GRAD', False)
|
||||||
@@ -538,7 +539,7 @@ class IPAdapterPlusEmbedder(BaseEmbedder):
|
|||||||
)
|
)
|
||||||
|
|
||||||
with FS.get_from(cfg.PRETRAINED_MODEL, wait_finish=True) as local_path:
|
with FS.get_from(cfg.PRETRAINED_MODEL, wait_finish=True) as local_path:
|
||||||
ckpt = torch.load(local_path, map_location='cpu')
|
ckpt = torch.load(local_path, map_location='cpu', weights_only=True)
|
||||||
self.image_proj_model.load_state_dict(ckpt['image_proj'],
|
self.image_proj_model.load_state_dict(ckpt['image_proj'],
|
||||||
strict=True)
|
strict=True)
|
||||||
|
|
||||||
@@ -645,7 +646,7 @@ class GeneralConditioner(BaseEmbedder):
|
|||||||
from safetensors.torch import load_file as load_safetensors
|
from safetensors.torch import load_file as load_safetensors
|
||||||
sd = load_safetensors(path)
|
sd = load_safetensors(path)
|
||||||
else:
|
else:
|
||||||
sd = torch.load(path, map_location='cpu')
|
sd = torch.load(path, map_location='cpu', weights_only=True)
|
||||||
new_sd = OrderedDict()
|
new_sd = OrderedDict()
|
||||||
for k, v in sd.items():
|
for k, v in sd.items():
|
||||||
ignored = False
|
ignored = False
|
||||||
|
|||||||
@@ -1,5 +1,7 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
# This file contains code that is adapted from
|
||||||
|
# https://github.com/black-forest-labs/flux.git
|
||||||
import torch
|
import torch
|
||||||
import transformers
|
import transformers
|
||||||
from scepter.modules.model.embedder.base_embedder import BaseEmbedder
|
from scepter.modules.model.embedder.base_embedder import BaseEmbedder
|
||||||
@@ -51,59 +53,53 @@ class HFEmbedder(BaseEmbedder):
|
|||||||
def __init__(self, cfg, logger=None):
|
def __init__(self, cfg, logger=None):
|
||||||
super().__init__(cfg, logger=logger)
|
super().__init__(cfg, logger=logger)
|
||||||
hf_model_cls = cfg.get('HF_MODEL_CLS', None)
|
hf_model_cls = cfg.get('HF_MODEL_CLS', None)
|
||||||
model_path = cfg.get('MODEL_PATH', None)
|
model_path = cfg.get("MODEL_PATH", None)
|
||||||
hf_tokenizer_cls = cfg.get('HF_TOKENIZER_CLS', None)
|
hf_tokenizer_cls = cfg.get('HF_TOKENIZER_CLS', None)
|
||||||
tokenizer_path = cfg.get('TOKENIZER_PATH', None)
|
tokenizer_path = cfg.get('TOKENIZER_PATH', None)
|
||||||
self.max_length = cfg.get('MAX_LENGTH', 77)
|
self.max_length = cfg.get('MAX_LENGTH', 77)
|
||||||
self.output_key = cfg.get('OUTPUT_KEY', 'last_hidden_state')
|
self.output_key = cfg.get("OUTPUT_KEY", "last_hidden_state")
|
||||||
self.d_type = cfg.get('D_TYPE', 'float')
|
self.d_type = cfg.get("D_TYPE", "float")
|
||||||
self.clean = cfg.get('CLEAN', 'whitespace')
|
self.clean = cfg.get("CLEAN", "whitespace")
|
||||||
self.batch_infer = cfg.get('BATCH_INFER', False)
|
self.batch_infer = cfg.get("BATCH_INFER", False)
|
||||||
|
self.added_identifier = cfg.get('ADDED_IDENTIFIER', None)
|
||||||
torch_dtype = getattr(torch, self.d_type)
|
torch_dtype = getattr(torch, self.d_type)
|
||||||
|
|
||||||
assert hf_model_cls is not None and hf_tokenizer_cls is not None
|
assert hf_model_cls is not None and hf_tokenizer_cls is not None
|
||||||
assert model_path is not None and tokenizer_path is not None
|
assert model_path is not None and tokenizer_path is not None
|
||||||
|
with FS.get_dir_to_local_dir(tokenizer_path, wait_finish=True) as local_path:
|
||||||
|
self.tokenizer = getattr(transformers, hf_tokenizer_cls).from_pretrained(local_path,
|
||||||
|
max_length = self.max_length,
|
||||||
|
torch_dtype = torch_dtype,
|
||||||
|
additional_special_tokens=self.added_identifier)
|
||||||
|
|
||||||
with FS.get_dir_to_local_dir(tokenizer_path,
|
with FS.get_dir_to_local_dir(model_path, wait_finish=True) as local_path:
|
||||||
wait_finish=True) as local_path:
|
self.hf_module = getattr(transformers, hf_model_cls).from_pretrained(local_path, torch_dtype = torch_dtype)
|
||||||
self.tokenizer = getattr(transformers,
|
|
||||||
hf_tokenizer_cls).from_pretrained(
|
|
||||||
local_path,
|
|
||||||
max_length=self.max_length,
|
|
||||||
torch_dtype=torch_dtype)
|
|
||||||
|
|
||||||
with FS.get_dir_to_local_dir(model_path,
|
|
||||||
wait_finish=True) as local_path:
|
|
||||||
self.hf_module = getattr(transformers,
|
|
||||||
hf_model_cls).from_pretrained(
|
|
||||||
local_path, torch_dtype=torch_dtype)
|
|
||||||
|
|
||||||
self.hf_module = self.hf_module.eval().requires_grad_(False)
|
self.hf_module = self.hf_module.eval().requires_grad_(False)
|
||||||
|
|
||||||
def forward(self, text: list[str], return_mask=False):
|
def forward(self, text: list[str], return_mask = False):
|
||||||
batch_encoding = self.tokenizer(
|
batch_encoding = self.tokenizer(
|
||||||
text,
|
text,
|
||||||
truncation=True,
|
truncation=True,
|
||||||
max_length=self.max_length,
|
max_length=self.max_length,
|
||||||
return_length=False,
|
return_length=False,
|
||||||
return_overflowing_tokens=False,
|
return_overflowing_tokens=False,
|
||||||
padding='max_length',
|
padding="max_length",
|
||||||
return_tensors='pt',
|
return_tensors="pt",
|
||||||
)
|
)
|
||||||
|
|
||||||
outputs = self.hf_module(
|
outputs = self.hf_module(
|
||||||
input_ids=batch_encoding['input_ids'].to(self.hf_module.device),
|
input_ids=batch_encoding["input_ids"].to(self.hf_module.device),
|
||||||
attention_mask=None,
|
attention_mask=None,
|
||||||
output_hidden_states=False,
|
output_hidden_states=False,
|
||||||
)
|
)
|
||||||
if return_mask:
|
if return_mask:
|
||||||
return outputs[
|
return outputs[self.output_key], batch_encoding['attention_mask'].to(self.hf_module.device)
|
||||||
self.output_key], batch_encoding['attention_mask'].to(
|
|
||||||
self.hf_module.device)
|
|
||||||
else:
|
else:
|
||||||
return outputs[self.output_key], None
|
return outputs[self.output_key], None
|
||||||
|
|
||||||
def encode(self, text, return_mask=False):
|
def encode(self, text, return_mask = False):
|
||||||
if isinstance(text, str):
|
if isinstance(text, str):
|
||||||
text = [text]
|
text = [text]
|
||||||
if self.clean:
|
if self.clean:
|
||||||
@@ -119,12 +115,36 @@ class HFEmbedder(BaseEmbedder):
|
|||||||
else:
|
else:
|
||||||
return torch.cat(cont, dim=0)
|
return torch.cat(cont, dim=0)
|
||||||
else:
|
else:
|
||||||
ret_data = self(text, return_mask=return_mask)
|
ret_data = self(text, return_mask = return_mask)
|
||||||
if return_mask:
|
if return_mask:
|
||||||
return ret_data
|
return ret_data
|
||||||
else:
|
else:
|
||||||
return ret_data[0]
|
return ret_data[0]
|
||||||
|
|
||||||
|
def encode_list(self, text_list, return_mask=True):
|
||||||
|
cont_list = []
|
||||||
|
mask_list = []
|
||||||
|
for pp in text_list:
|
||||||
|
cont = self.encode(pp, return_mask=return_mask)
|
||||||
|
cont_list.append(cont[0]) if return_mask else cont_list.append(cont)
|
||||||
|
mask_list.append(cont[1]) if return_mask else mask_list.append(None)
|
||||||
|
if return_mask:
|
||||||
|
return cont_list, mask_list
|
||||||
|
else:
|
||||||
|
return cont_list
|
||||||
|
|
||||||
|
def encode_list_of_list(self, text_list, return_mask=True):
|
||||||
|
cont_list = []
|
||||||
|
mask_list = []
|
||||||
|
for pp in text_list:
|
||||||
|
cont = self.encode_list(pp, return_mask=return_mask)
|
||||||
|
cont_list.append(cont[0]) if return_mask else cont_list.append(cont)
|
||||||
|
mask_list.append(cont[1]) if return_mask else mask_list.append(None)
|
||||||
|
if return_mask:
|
||||||
|
return cont_list, mask_list
|
||||||
|
else:
|
||||||
|
return cont_list
|
||||||
|
|
||||||
def _clean(self, text):
|
def _clean(self, text):
|
||||||
if self.clean == 'whitespace':
|
if self.clean == 'whitespace':
|
||||||
text = whitespace_clean(basic_clean(text))
|
text = whitespace_clean(basic_clean(text))
|
||||||
@@ -133,7 +153,6 @@ class HFEmbedder(BaseEmbedder):
|
|||||||
elif self.clean == 'canonicalize':
|
elif self.clean == 'canonicalize':
|
||||||
text = canonicalize(basic_clean(text))
|
text = canonicalize(basic_clean(text))
|
||||||
return text
|
return text
|
||||||
|
|
||||||
@staticmethod
|
@staticmethod
|
||||||
def get_config_template():
|
def get_config_template():
|
||||||
return dict_to_yaml('EMBEDDER',
|
return dict_to_yaml('EMBEDDER',
|
||||||
@@ -141,28 +160,49 @@ class HFEmbedder(BaseEmbedder):
|
|||||||
HFEmbedder.para_dict,
|
HFEmbedder.para_dict,
|
||||||
set_name=True)
|
set_name=True)
|
||||||
|
|
||||||
|
|
||||||
@EMBEDDERS.register_class()
|
@EMBEDDERS.register_class()
|
||||||
class T5PlusClipFluxEmbedder(BaseEmbedder):
|
class T5PlusClipFluxEmbedder(BaseEmbedder):
|
||||||
"""
|
"""
|
||||||
Uses the OpenCLIP transformer encoder for text
|
Uses the OpenCLIP transformer encoder for text
|
||||||
"""
|
"""
|
||||||
para_dict = {'T5_MODEL': {}, 'CLIP_MODEL': {}}
|
para_dict = {
|
||||||
|
'T5_MODEL': {},
|
||||||
|
'CLIP_MODEL': {}
|
||||||
|
}
|
||||||
|
|
||||||
def __init__(self, cfg, logger=None):
|
def __init__(self, cfg, logger=None):
|
||||||
super().__init__(cfg, logger=logger)
|
super().__init__(cfg, logger=logger)
|
||||||
self.t5_model = EMBEDDERS.build(cfg.T5_MODEL, logger=logger)
|
self.t5_model = EMBEDDERS.build(cfg.T5_MODEL, logger=logger)
|
||||||
self.clip_model = EMBEDDERS.build(cfg.CLIP_MODEL, logger=logger)
|
self.clip_model = EMBEDDERS.build(cfg.CLIP_MODEL, logger=logger)
|
||||||
|
|
||||||
def encode(self, text):
|
def encode(self, text, return_mask = False):
|
||||||
t5_embeds = self.t5_model.encode(text, return_mask=False)
|
t5_embeds = self.t5_model.encode(text, return_mask = return_mask)
|
||||||
clip_embeds = self.clip_model.encode(text, return_mask=False)
|
clip_embeds = self.clip_model.encode(text, return_mask = return_mask)
|
||||||
# change embedding strategy here
|
# change embedding strategy here
|
||||||
return {
|
return {
|
||||||
'context': t5_embeds,
|
'context': t5_embeds,
|
||||||
'y': clip_embeds,
|
'y': clip_embeds,
|
||||||
}
|
}
|
||||||
|
|
||||||
|
def encode_list(self, text, return_mask = False):
|
||||||
|
t5_embeds = self.t5_model.encode_list(text, return_mask = return_mask)
|
||||||
|
clip_embeds = self.clip_model.encode_list(text, return_mask = return_mask)
|
||||||
|
# change embedding strategy here
|
||||||
|
return {
|
||||||
|
'context': t5_embeds,
|
||||||
|
'y': clip_embeds,
|
||||||
|
}
|
||||||
|
|
||||||
|
def encode_list_of_list(self, text, return_mask = False):
|
||||||
|
t5_embeds = self.t5_model.encode_list_of_list(text, return_mask = return_mask)
|
||||||
|
clip_embeds = self.clip_model.encode_list_of_list(text, return_mask = return_mask)
|
||||||
|
# change embedding strategy here
|
||||||
|
return {
|
||||||
|
'context': t5_embeds,
|
||||||
|
'y': clip_embeds,
|
||||||
|
}
|
||||||
|
|
||||||
|
|
||||||
@staticmethod
|
@staticmethod
|
||||||
def get_config_template():
|
def get_config_template():
|
||||||
return dict_to_yaml('EMBEDDER',
|
return dict_to_yaml('EMBEDDER',
|
||||||
|
|||||||
@@ -1,5 +1,25 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.model.head.classifier_head import (
|
from typing import TYPE_CHECKING
|
||||||
ClassifierHead, CosineLinearHead, TransformerHead, TransformerHeadx2,
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
VideoClassifierHead, VideoClassifierHeadx2)
|
|
||||||
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.model.head.classifier_head import (
|
||||||
|
ClassifierHead, CosineLinearHead, TransformerHead, TransformerHeadx2,
|
||||||
|
VideoClassifierHead, VideoClassifierHeadx2)
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'classifier_head': ['ClassifierHead', 'CosineLinearHead',
|
||||||
|
'TransformerHead', 'TransformerHeadx2',
|
||||||
|
'VideoClassifierHead', 'VideoClassifierHeadx2']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -1,4 +1,23 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.model.loss.base_losses import CrossEntropy
|
from typing import TYPE_CHECKING
|
||||||
from scepter.modules.model.loss.rec_loss import MinSNRLoss, ReconstructLoss
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.model.loss.base_losses import CrossEntropy
|
||||||
|
from scepter.modules.model.loss.rec_loss import MinSNRLoss, ReconstructLoss
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'base_losses': ['CrossEntropy'],
|
||||||
|
'rec_loss': ['MinSNRLoss', 'ReconstructLoss']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -1,5 +1,23 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.model.metric.classification import (AccuracyMetric,
|
from typing import TYPE_CHECKING
|
||||||
EnsembleAccuracyMetric
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
)
|
|
||||||
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.model.metric.classification import (AccuracyMetric,
|
||||||
|
EnsembleAccuracyMetric
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'classification': ['AccuracyMetric', 'EnsembleAccuracyMetric']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -1,5 +1,24 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.model.neck.global_average_pooling import \
|
from typing import TYPE_CHECKING
|
||||||
GlobalAveragePooling
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
from scepter.modules.model.neck.identity import Identity
|
|
||||||
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.model.neck.global_average_pooling import \
|
||||||
|
GlobalAveragePooling
|
||||||
|
from scepter.modules.model.neck.identity import Identity
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'global_average_pooling': ['GlobalAveragePooling'],
|
||||||
|
'identity': ['Identity']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -1,9 +1,32 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.model.network.autoencoder import ae_kl
|
from typing import TYPE_CHECKING
|
||||||
from scepter.modules.model.network.classifier import Classifier
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
from scepter.modules.model.network.diffusion import (diffusion, schedules,
|
|
||||||
solvers)
|
|
||||||
from scepter.modules.model.network.ldm import (ldm, ldm_edit, ldm_pixart,
|
if TYPE_CHECKING:
|
||||||
ldm_sce, ldm_sd3, ldm_xl,
|
from scepter.modules.model.network.autoencoder import ae_kl
|
||||||
ldm_flux)
|
from scepter.modules.model.network.classifier import Classifier
|
||||||
|
from scepter.modules.model.network.diffusion import (diffusion, schedules,
|
||||||
|
solvers)
|
||||||
|
from scepter.modules.model.network.ldm import (ldm, ldm_edit, ldm_pixart,
|
||||||
|
ldm_sce, ldm_sd3, ldm_xl,
|
||||||
|
ldm_flux)
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'autoencoder': ['ae_kl'],
|
||||||
|
'classifier': ['Classifier'],
|
||||||
|
'diffusion': ['diffusion', 'schedules', 'solvers'],
|
||||||
|
'ldm': ['ldm', 'ldm_edit', 'ldm_pixart',
|
||||||
|
'ldm_sce', 'ldm_sd3', 'ldm_xl',
|
||||||
|
'ldm_flux']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -1,4 +1,23 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.model.network.autoencoder.ae_kl import AutoencoderKL
|
from typing import TYPE_CHECKING
|
||||||
from scepter.modules.model.network.autoencoder.ae_kl_cogvideox import AutoencoderKLCogVideoX
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.model.network.autoencoder.ae_kl import AutoencoderKL
|
||||||
|
from scepter.modules.model.network.autoencoder.ae_kl_cogvideox import AutoencoderKLCogVideoX
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'ae_kl': ['AutoencoderKL'],
|
||||||
|
'ae_kl_cogvideox': ['AutoencoderKLCogVideoX']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -129,7 +129,7 @@ class AutoencoderKL(TrainModule):
|
|||||||
for k in f.keys():
|
for k in f.keys():
|
||||||
sd[k] = f.get_tensor(k)
|
sd[k] = f.get_tensor(k)
|
||||||
else:
|
else:
|
||||||
sd = torch.load(path, map_location='cpu')
|
sd = torch.load(path, map_location='cpu', weights_only=True)
|
||||||
if path.find('.pt') > -1 and 'state_dict' in sd:
|
if path.find('.pt') > -1 and 'state_dict' in sd:
|
||||||
sd = sd['state_dict']
|
sd = sd['state_dict']
|
||||||
elif path.find('.ckpt') > -1 and 'state_dict' in sd:
|
elif path.find('.ckpt') > -1 and 'state_dict' in sd:
|
||||||
@@ -373,7 +373,7 @@ class AutoencoderKLFlux(TrainModule):
|
|||||||
for k in f.keys():
|
for k in f.keys():
|
||||||
sd[k] = f.get_tensor(k)
|
sd[k] = f.get_tensor(k)
|
||||||
else:
|
else:
|
||||||
sd = torch.load(path, map_location="cpu")
|
sd = torch.load(path, map_location="cpu", weights_only=True)
|
||||||
if path.find('.pt') > -1 and 'state_dict' in sd:
|
if path.find('.pt') > -1 and 'state_dict' in sd:
|
||||||
sd = sd['state_dict']
|
sd = sd['state_dict']
|
||||||
elif path.find('.ckpt') > -1 and 'state_dict' in sd:
|
elif path.find('.ckpt') > -1 and 'state_dict' in sd:
|
||||||
|
|||||||
@@ -1591,7 +1591,7 @@ class AutoencoderKLCogVideoX(TrainModule):
|
|||||||
from safetensors.torch import load_file as load_safetensors
|
from safetensors.torch import load_file as load_safetensors
|
||||||
ckpt = load_safetensors(local_model)
|
ckpt = load_safetensors(local_model)
|
||||||
else:
|
else:
|
||||||
ckpt = torch.load(local_model, map_location='cpu')
|
ckpt = torch.load(local_model, map_location='cpu', weights_only=True)
|
||||||
missing, unexpected = self.load_state_dict(ckpt, strict=False)
|
missing, unexpected = self.load_state_dict(ckpt, strict=False)
|
||||||
if we.rank == 0:
|
if we.rank == 0:
|
||||||
self.logger.info(
|
self.logger.info(
|
||||||
|
|||||||
@@ -1,4 +1,22 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.model.network.diffusion import (diffusion, schedules,
|
from typing import TYPE_CHECKING
|
||||||
solvers)
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.model.network.diffusion import (diffusion, schedules,
|
||||||
|
solvers)
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'diffusion': ['diffusion', 'schedules', 'solvers']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -239,7 +239,7 @@ class GaussianDiffusion(object):
|
|||||||
percentile=None,
|
percentile=None,
|
||||||
cat_uc=False,
|
cat_uc=False,
|
||||||
**kwargs):
|
**kwargs):
|
||||||
"""
|
r"""
|
||||||
Apply one step of denoising from the posterior distribution q(x_s | x_t, x0).
|
Apply one step of denoising from the posterior distribution q(x_s | x_t, x0).
|
||||||
Since x0 is not available, estimate the denoising results using the learned
|
Since x0 is not available, estimate the denoising results using the learned
|
||||||
distribution p(x_s | x_t, \hat{x}_0 == f(x_t)). # noqa
|
distribution p(x_s | x_t, \hat{x}_0 == f(x_t)). # noqa
|
||||||
|
|||||||
@@ -1,15 +1,44 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.model.network.ldm.ldm import LatentDiffusion
|
from typing import TYPE_CHECKING
|
||||||
from scepter.modules.model.network.ldm.ldm_ace import (LatentDiffusionACE,
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
LatentDiffusionACERefiner)
|
|
||||||
from scepter.modules.model.network.ldm.ldm_edit import LatentDiffusionEdit
|
|
||||||
from scepter.modules.model.network.ldm.ldm_pixart import LatentDiffusionPixart
|
if TYPE_CHECKING:
|
||||||
from scepter.modules.model.network.ldm.ldm_sce import (
|
from scepter.modules.model.network.ldm.ldm import LatentDiffusion
|
||||||
LatentDiffusionSCEControl, LatentDiffusionSCETuning,
|
from scepter.modules.model.network.ldm.ldm_ace import (LatentDiffusionACE,
|
||||||
LatentDiffusionXLSCEControl, LatentDiffusionXLSCETuning)
|
LatentDiffusionACERefiner)
|
||||||
from scepter.modules.model.network.ldm.ldm_sd3 import LatentDiffusionSD3
|
from scepter.modules.model.network.ldm.ldm_edit import LatentDiffusionEdit
|
||||||
from scepter.modules.model.network.ldm.ldm_xl import LatentDiffusionXL
|
from scepter.modules.model.network.ldm.ldm_pixart import LatentDiffusionPixart
|
||||||
from scepter.modules.model.network.ldm.ldm_cogvideox import LatentDiffusionCogVideoX
|
from scepter.modules.model.network.ldm.ldm_sce import (
|
||||||
from scepter.modules.model.network.ldm.ldm_flux import (LatentDiffusionFlux,
|
LatentDiffusionSCEControl, LatentDiffusionSCETuning,
|
||||||
LatentDiffusionFluxMR)
|
LatentDiffusionXLSCEControl, LatentDiffusionXLSCETuning)
|
||||||
|
from scepter.modules.model.network.ldm.ldm_sd3 import LatentDiffusionSD3
|
||||||
|
from scepter.modules.model.network.ldm.ldm_xl import LatentDiffusionXL
|
||||||
|
from scepter.modules.model.network.ldm.ldm_cogvideox import LatentDiffusionCogVideoX
|
||||||
|
from scepter.modules.model.network.ldm.ldm_flux import (LatentDiffusionFlux,
|
||||||
|
LatentDiffusionFluxMR)
|
||||||
|
from scepter.modules.model.network.ldm.ldm_ace_plus import LatentDiffusionACEPlus
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'ldm': ['LatentDiffusion'],
|
||||||
|
'ldm_ace': ['LatentDiffusionACE', 'LatentDiffusionACERefiner'],
|
||||||
|
'ldm_edit': ['LatentDiffusionEdit'],
|
||||||
|
'ldm_pixart': ['LatentDiffusionPixart'],
|
||||||
|
'ldm_sce': ['LatentDiffusionSCEControl', 'LatentDiffusionSCETuning',
|
||||||
|
'LatentDiffusionXLSCEControl', 'LatentDiffusionXLSCETuning'],
|
||||||
|
'ldm_sd3': ['LatentDiffusionSD3'],
|
||||||
|
'ldm_xl': ['LatentDiffusionXL'],
|
||||||
|
'ldm_cogvideox': ['LatentDiffusionCogVideoX'],
|
||||||
|
'ldm_flux': ['LatentDiffusionFlux', 'LatentDiffusionFluxMR'],
|
||||||
|
'ldm_ace_plus': ['LatentDiffusionACEPlus'],
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -200,7 +200,7 @@ class LatentDiffusion(TrainModule):
|
|||||||
from safetensors.torch import load_file as load_safetensors
|
from safetensors.torch import load_file as load_safetensors
|
||||||
sd = load_safetensors(path)
|
sd = load_safetensors(path)
|
||||||
else:
|
else:
|
||||||
sd = torch.load(path, map_location='cpu')
|
sd = torch.load(path, map_location='cpu',weights_only=True)
|
||||||
new_sd = OrderedDict()
|
new_sd = OrderedDict()
|
||||||
for k, v in sd.items():
|
for k, v in sd.items():
|
||||||
ignored = False
|
ignored = False
|
||||||
|
|||||||
@@ -95,8 +95,8 @@ class LatentDiffusionACE(LatentDiffusion):
|
|||||||
return batch_data_list
|
return batch_data_list
|
||||||
|
|
||||||
def forward_train(self,
|
def forward_train(self,
|
||||||
edit_image=[],
|
src_image_list=[],
|
||||||
edit_image_mask=[],
|
src_mask_list=[],
|
||||||
image=None,
|
image=None,
|
||||||
image_mask=None,
|
image_mask=None,
|
||||||
noise=None,
|
noise=None,
|
||||||
@@ -114,8 +114,8 @@ class LatentDiffusionACE(LatentDiffusion):
|
|||||||
Returns:
|
Returns:
|
||||||
'''
|
'''
|
||||||
assert check_list_of_list(prompt) and check_list_of_list(
|
assert check_list_of_list(prompt) and check_list_of_list(
|
||||||
edit_image) and check_list_of_list(edit_image_mask)
|
src_image_list) and check_list_of_list(src_mask_list)
|
||||||
assert len(edit_image) == len(edit_image_mask) == len(prompt)
|
assert len(src_image_list) == len(src_mask_list) == len(prompt)
|
||||||
assert self.cond_stage_model is not None
|
assert self.cond_stage_model is not None
|
||||||
gc_seg = kwargs.pop('gc_seg', [])
|
gc_seg = kwargs.pop('gc_seg', [])
|
||||||
gc_seg = int(gc_seg[0]) if len(gc_seg) > 0 else 0
|
gc_seg = int(gc_seg[0]) if len(gc_seg) > 0 else 0
|
||||||
@@ -143,13 +143,13 @@ class LatentDiffusionACE(LatentDiffusion):
|
|||||||
'encode_list_of_list')(prompt_, return_mask=True)
|
'encode_list_of_list')(prompt_, return_mask=True)
|
||||||
except Exception as e:
|
except Exception as e:
|
||||||
print(e, prompt_)
|
print(e, prompt_)
|
||||||
cont, cont_mask = self.cond_stage_embeddings(prompt, edit_image, cont,
|
cont, cont_mask = self.cond_stage_embeddings(prompt, src_image_list, cont,
|
||||||
cont_mask)
|
cont_mask)
|
||||||
context['crossattn'] = cont
|
context['crossattn'] = cont
|
||||||
|
|
||||||
# process edit image & edit image mask
|
# process edit image & edit image mask
|
||||||
edit_image = [to_device(i, strict=False) for i in edit_image]
|
edit_image = [to_device(i, strict=False) for i in src_image_list]
|
||||||
edit_image_mask = [to_device(i, strict=False) for i in edit_image_mask]
|
edit_image_mask = [to_device(i, strict=False) for i in src_mask_list]
|
||||||
e_img, e_mask = [], []
|
e_img, e_mask = [], []
|
||||||
for u, m in zip(edit_image, edit_image_mask):
|
for u, m in zip(edit_image, edit_image_mask):
|
||||||
if m is None:
|
if m is None:
|
||||||
@@ -185,8 +185,8 @@ class LatentDiffusionACE(LatentDiffusion):
|
|||||||
|
|
||||||
@torch.no_grad()
|
@torch.no_grad()
|
||||||
def forward_test(self,
|
def forward_test(self,
|
||||||
edit_image=[],
|
src_image_list=[],
|
||||||
edit_image_mask=[],
|
src_mask_list=[],
|
||||||
image=None,
|
image=None,
|
||||||
image_mask=None,
|
image_mask=None,
|
||||||
prompt=[],
|
prompt=[],
|
||||||
@@ -200,8 +200,8 @@ class LatentDiffusionACE(LatentDiffusion):
|
|||||||
**kwargs):
|
**kwargs):
|
||||||
|
|
||||||
assert check_list_of_list(prompt) and check_list_of_list(
|
assert check_list_of_list(prompt) and check_list_of_list(
|
||||||
edit_image) and check_list_of_list(edit_image_mask)
|
src_image_list) and check_list_of_list(src_mask_list)
|
||||||
assert len(edit_image) == len(edit_image_mask) == len(prompt)
|
assert len(src_image_list) == len(src_mask_list) == len(prompt)
|
||||||
assert self.cond_stage_model is not None
|
assert self.cond_stage_model is not None
|
||||||
# gc_seg is unused
|
# gc_seg is unused
|
||||||
kwargs.pop('gc_seg', -1)
|
kwargs.pop('gc_seg', -1)
|
||||||
@@ -209,7 +209,7 @@ class LatentDiffusionACE(LatentDiffusion):
|
|||||||
context, null_context = {}, {}
|
context, null_context = {}, {}
|
||||||
|
|
||||||
prompt, n_prompt, image, image_mask, edit_image, edit_image_mask = self.limit_batch_data(
|
prompt, n_prompt, image, image_mask, edit_image, edit_image_mask = self.limit_batch_data(
|
||||||
[prompt, n_prompt, image, image_mask, edit_image, edit_image_mask],
|
[prompt, n_prompt, image, image_mask, src_image_list, src_mask_list],
|
||||||
log_num)
|
log_num)
|
||||||
g = torch.Generator(device=we.device_id)
|
g = torch.Generator(device=we.device_id)
|
||||||
seed = seed if seed >= 0 else random.randint(0, 2**32 - 1)
|
seed = seed if seed >= 0 else random.randint(0, 2**32 - 1)
|
||||||
@@ -368,8 +368,8 @@ class LatentDiffusionACERefiner(LatentDiffusionACE):
|
|||||||
self.enhence_sampler_cfg = None
|
self.enhence_sampler_cfg = None
|
||||||
|
|
||||||
def forward_sample(self,
|
def forward_sample(self,
|
||||||
edit_image=[],
|
src_image_list=[],
|
||||||
edit_mask=[],
|
src_mask_list=[],
|
||||||
noise=None,
|
noise=None,
|
||||||
cond_mask=[],
|
cond_mask=[],
|
||||||
x_shapes=[],
|
x_shapes=[],
|
||||||
@@ -414,15 +414,15 @@ class LatentDiffusionACERefiner(LatentDiffusionACE):
|
|||||||
# with torch.autocast(device_type="cuda", enabled=True, dtype=torch.bfloat16):
|
# with torch.autocast(device_type="cuda", enabled=True, dtype=torch.bfloat16):
|
||||||
|
|
||||||
cont, cont_mask = getattr(self.cond_stage_model, 'encode_list')(prompt, return_mask=True)
|
cont, cont_mask = getattr(self.cond_stage_model, 'encode_list')(prompt, return_mask=True)
|
||||||
cont, cont_mask = self.cond_stage_embeddings(prompt, edit_image, cont, cont_mask)
|
cont, cont_mask = self.cond_stage_embeddings(prompt, src_image_list, cont, cont_mask)
|
||||||
null_cont, null_cont_mask = getattr(self.cond_stage_model, 'encode_list')(n_prompt, return_mask=True)
|
null_cont, null_cont_mask = getattr(self.cond_stage_model, 'encode_list')(n_prompt, return_mask=True)
|
||||||
null_cont, null_cont_mask = self.cond_stage_embeddings(prompt, edit_image, null_cont, null_cont_mask)
|
null_cont, null_cont_mask = self.cond_stage_embeddings(prompt, src_image_list, null_cont, null_cont_mask)
|
||||||
context['crossattn'] = cont
|
context['crossattn'] = cont
|
||||||
null_context['crossattn'] = null_cont
|
null_context['crossattn'] = null_cont
|
||||||
|
|
||||||
|
|
||||||
null_context['edit'] = context['edit'] = edit_image
|
null_context['edit'] = context['edit'] = src_image_list
|
||||||
null_context['edit_mask'] = context['edit_mask'] = edit_mask
|
null_context['edit_mask'] = context['edit_mask'] = src_mask_list
|
||||||
|
|
||||||
# process sample
|
# process sample
|
||||||
model = self.model_ema if self.use_ema and self.eval_ema else self.model
|
model = self.model_ema if self.use_ema and self.eval_ema else self.model
|
||||||
@@ -478,8 +478,8 @@ class LatentDiffusionACERefiner(LatentDiffusionACE):
|
|||||||
|
|
||||||
@torch.no_grad()
|
@torch.no_grad()
|
||||||
def forward_test(self,
|
def forward_test(self,
|
||||||
edit_image=[],
|
src_image_list=[],
|
||||||
edit_image_mask=[],
|
src_mask_list=[],
|
||||||
image=None,
|
image=None,
|
||||||
image_mask=None,
|
image_mask=None,
|
||||||
prompt=[],
|
prompt=[],
|
||||||
@@ -493,13 +493,13 @@ class LatentDiffusionACERefiner(LatentDiffusionACE):
|
|||||||
enhance_scale=0.99,
|
enhance_scale=0.99,
|
||||||
log_num=-1,
|
log_num=-1,
|
||||||
**kwargs):
|
**kwargs):
|
||||||
assert check_list_of_list(prompt) and check_list_of_list(edit_image) and check_list_of_list(edit_image_mask)
|
assert check_list_of_list(prompt) and check_list_of_list(src_image_list) and check_list_of_list(src_mask_list)
|
||||||
assert len(edit_image) == len(edit_image_mask) == len(prompt)
|
assert len(src_image_list) == len(src_mask_list) == len(prompt)
|
||||||
assert self.cond_stage_model is not None
|
assert self.cond_stage_model is not None
|
||||||
# gc_seg is unused
|
# gc_seg is unused
|
||||||
kwargs.pop("gc_seg", -1)
|
kwargs.pop("gc_seg", -1)
|
||||||
prompt, n_prompt, image, image_mask, edit_image, edit_image_mask = self.limit_batch_data(
|
prompt, n_prompt, image, image_mask, edit_image, edit_image_mask = self.limit_batch_data(
|
||||||
[prompt, n_prompt, image, image_mask, edit_image, edit_image_mask], log_num)
|
[prompt, n_prompt, image, image_mask, src_image_list, src_mask_list], log_num)
|
||||||
|
|
||||||
prompt = [[pp] if isinstance(pp, str) else pp for pp in prompt]
|
prompt = [[pp] if isinstance(pp, str) else pp for pp in prompt]
|
||||||
|
|
||||||
|
|||||||
@@ -0,0 +1,371 @@
|
|||||||
|
# -*- coding: utf-8 -*-
|
||||||
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
import copy
|
||||||
|
import random
|
||||||
|
from contextlib import nullcontext
|
||||||
|
|
||||||
|
import torch
|
||||||
|
import torch.nn.functional as F
|
||||||
|
from torch.distributed.fsdp import FullyShardedDataParallel
|
||||||
|
|
||||||
|
from einops import rearrange
|
||||||
|
from scepter.modules.model.network.ldm import LatentDiffusionFluxMR
|
||||||
|
from scepter.modules.model.registry import MODELS
|
||||||
|
from scepter.modules.model.utils.basic_utils import (
|
||||||
|
check_list_of_list, limit_batch_data, pack_imagelist_into_tensor,
|
||||||
|
to_device, unpack_tensor_into_imagelist)
|
||||||
|
from scepter.modules.utils.config import dict_to_yaml
|
||||||
|
from scepter.modules.utils.distribute import we
|
||||||
|
|
||||||
|
|
||||||
|
@MODELS.register_class()
|
||||||
|
class LatentDiffusionACEPlus(LatentDiffusionFluxMR):
|
||||||
|
para_dict = {}
|
||||||
|
para_dict.update(LatentDiffusionFluxMR.para_dict)
|
||||||
|
|
||||||
|
def resize_func(self, x, size):
|
||||||
|
if x is None:
|
||||||
|
return x
|
||||||
|
return F.interpolate(x.unsqueeze(0), size=size, mode='nearest-exact')
|
||||||
|
|
||||||
|
def parse_ref_and_edit(
|
||||||
|
self,
|
||||||
|
src_image,
|
||||||
|
src_image_mask,
|
||||||
|
text_embedding,
|
||||||
|
# text_mask,
|
||||||
|
edit_id):
|
||||||
|
edit_image = []
|
||||||
|
edit_mask = []
|
||||||
|
ref_image = []
|
||||||
|
ref_mask = []
|
||||||
|
ref_context = []
|
||||||
|
ref_y = []
|
||||||
|
ref_id = []
|
||||||
|
txt = []
|
||||||
|
txt_y = []
|
||||||
|
for sample_id, (
|
||||||
|
one_src,
|
||||||
|
one_src_mask,
|
||||||
|
one_text_embedding,
|
||||||
|
one_text_y,
|
||||||
|
# one_text_mask,
|
||||||
|
one_edit_id) in enumerate(
|
||||||
|
zip(
|
||||||
|
src_image,
|
||||||
|
src_image_mask,
|
||||||
|
text_embedding['context'],
|
||||||
|
text_embedding['y'],
|
||||||
|
# text_mask,
|
||||||
|
edit_id)):
|
||||||
|
ref_id.append([i for i in range(len(one_src))])
|
||||||
|
if hasattr(self,
|
||||||
|
'ref_cond_stage_model') and self.ref_cond_stage_model:
|
||||||
|
ref_image.append(
|
||||||
|
self.ref_cond_stage_model.encode_list([
|
||||||
|
((i + 1.0) / 2.0 * 255).type(torch.uint8)
|
||||||
|
for i in one_src
|
||||||
|
]))
|
||||||
|
else:
|
||||||
|
ref_image.append(one_src)
|
||||||
|
ref_mask.append(one_src_mask)
|
||||||
|
# process edit image & edit image mask
|
||||||
|
current_edit_image = to_device([one_src[i] for i in one_edit_id],
|
||||||
|
strict=False)
|
||||||
|
current_edit_image = [
|
||||||
|
v.squeeze(0)
|
||||||
|
for v in self.encode_first_stage(current_edit_image)
|
||||||
|
]
|
||||||
|
current_edit_image_mask = to_device(
|
||||||
|
[one_src_mask[i] for i in one_edit_id], strict=False)
|
||||||
|
current_edit_image_mask = [
|
||||||
|
self.reshape_func(m).squeeze(0)
|
||||||
|
for m in current_edit_image_mask
|
||||||
|
]
|
||||||
|
|
||||||
|
edit_image.append(current_edit_image)
|
||||||
|
edit_mask.append(current_edit_image_mask)
|
||||||
|
ref_context.append(one_text_embedding[:len(ref_id[-1])])
|
||||||
|
ref_y.append(one_text_y[:len(ref_id[-1])])
|
||||||
|
if not sum(len(src_) for src_ in src_image) > 0:
|
||||||
|
ref_image = None
|
||||||
|
ref_context = None
|
||||||
|
ref_y = None
|
||||||
|
for sample_id, (one_text_embedding, one_text_y) in enumerate(
|
||||||
|
zip(text_embedding['context'], text_embedding['y'])):
|
||||||
|
txt.append(one_text_embedding[-1].squeeze(0))
|
||||||
|
txt_y.append(one_text_y[-1])
|
||||||
|
return {
|
||||||
|
'edit': edit_image,
|
||||||
|
'edit_mask': edit_mask,
|
||||||
|
'edit_id': edit_id,
|
||||||
|
'ref_context': ref_context,
|
||||||
|
'ref_y': ref_y,
|
||||||
|
'context': txt,
|
||||||
|
'y': txt_y,
|
||||||
|
'ref_x': ref_image,
|
||||||
|
'ref_mask': ref_mask,
|
||||||
|
'ref_id': ref_id
|
||||||
|
}
|
||||||
|
|
||||||
|
def reshape_func(self, mask):
|
||||||
|
mask = mask.to(torch.bfloat16)
|
||||||
|
mask = mask.view((-1, mask.shape[-2], mask.shape[-1]))
|
||||||
|
mask = rearrange(
|
||||||
|
mask,
|
||||||
|
'c (h ph) (w pw) -> c (ph pw) h w',
|
||||||
|
ph=8,
|
||||||
|
pw=8,
|
||||||
|
)
|
||||||
|
return mask
|
||||||
|
|
||||||
|
def forward_train(self,
|
||||||
|
src_image_list=[],
|
||||||
|
src_mask_list=[],
|
||||||
|
edit_id=[],
|
||||||
|
image=None,
|
||||||
|
image_mask=None,
|
||||||
|
noise=None,
|
||||||
|
prompt=[],
|
||||||
|
**kwargs):
|
||||||
|
'''
|
||||||
|
Args:
|
||||||
|
src_image: list of list of src_image
|
||||||
|
src_image_mask: list of list of src_image_mask
|
||||||
|
image: target image
|
||||||
|
image_mask: target image mask
|
||||||
|
noise: default is None, generate automaticly
|
||||||
|
ref_prompt: list of list of text
|
||||||
|
prompt: list of text
|
||||||
|
**kwargs:
|
||||||
|
Returns:
|
||||||
|
'''
|
||||||
|
assert check_list_of_list(src_image_list) and check_list_of_list(
|
||||||
|
src_mask_list)
|
||||||
|
assert self.cond_stage_model is not None
|
||||||
|
|
||||||
|
gc_seg = kwargs.pop('gc_seg', [])
|
||||||
|
gc_seg = int(gc_seg[0]) if len(gc_seg) > 0 else 0
|
||||||
|
align = kwargs.pop('align', [])
|
||||||
|
prompt_ = [[pp] if isinstance(pp, str) else pp for pp in prompt]
|
||||||
|
if len(align) < 1:
|
||||||
|
align = [0] * len(prompt_)
|
||||||
|
context = getattr(self.cond_stage_model,
|
||||||
|
'encode_list_of_list')(prompt_)
|
||||||
|
guide_scale = self.guide_scale
|
||||||
|
if guide_scale is not None:
|
||||||
|
guide_scale = torch.full((len(prompt_), ),
|
||||||
|
guide_scale,
|
||||||
|
device=we.device_id)
|
||||||
|
else:
|
||||||
|
guide_scale = None
|
||||||
|
# image and image_mask
|
||||||
|
# print("is list of list", check_list_of_list(image))
|
||||||
|
if check_list_of_list(image):
|
||||||
|
image = [to_device(ix) for ix in image]
|
||||||
|
x_start = [self.encode_first_stage(ix, **kwargs) for ix in image]
|
||||||
|
noise = [[torch.randn_like(ii) for ii in ix] for ix in x_start]
|
||||||
|
x_start = [torch.cat(ix, dim=-1) for ix in x_start]
|
||||||
|
noise = [torch.cat(ix, dim=-1) for ix in noise]
|
||||||
|
|
||||||
|
noise, _ = pack_imagelist_into_tensor(noise)
|
||||||
|
|
||||||
|
image_mask = [to_device(im, strict=False) for im in image_mask]
|
||||||
|
x_mask = [[self.reshape_func(i).squeeze(0)
|
||||||
|
for i in im] if im is not None else [None] * len(ix)
|
||||||
|
for ix, im in zip(image, image_mask)]
|
||||||
|
x_mask = [torch.cat(im, dim=-1) for im in x_mask]
|
||||||
|
else:
|
||||||
|
image = to_device(image)
|
||||||
|
x_start = self.encode_first_stage(image, **kwargs)
|
||||||
|
image_mask = to_device(image_mask, strict=False)
|
||||||
|
x_mask = [self.reshape_func(i).squeeze(0) for i in image_mask
|
||||||
|
] if image_mask is not None else [None] * len(image)
|
||||||
|
loss_mask, _ = pack_imagelist_into_tensor(
|
||||||
|
tuple(
|
||||||
|
torch.ones_like(ix, dtype=torch.bool, device=ix.device)
|
||||||
|
for ix in x_start))
|
||||||
|
x_start, x_shapes = pack_imagelist_into_tensor(x_start)
|
||||||
|
context['x_shapes'] = x_shapes
|
||||||
|
context['align'] = align
|
||||||
|
# process image mask
|
||||||
|
|
||||||
|
context['x_mask'] = x_mask
|
||||||
|
ref_edit_context = self.parse_ref_and_edit(src_image_list,
|
||||||
|
src_mask_list, context,
|
||||||
|
edit_id)
|
||||||
|
context.update(ref_edit_context)
|
||||||
|
|
||||||
|
teacher_context = copy.deepcopy(context)
|
||||||
|
teacher_context['context'] = torch.cat(teacher_context['context'],
|
||||||
|
dim=0)
|
||||||
|
teacher_context['y'] = torch.cat(teacher_context['y'], dim=0)
|
||||||
|
loss = self.diffusion.loss(x_0=x_start,
|
||||||
|
model=self.model,
|
||||||
|
model_kwargs={
|
||||||
|
'cond': context,
|
||||||
|
'gc_seg': gc_seg,
|
||||||
|
'guidance': guide_scale
|
||||||
|
},
|
||||||
|
noise=noise,
|
||||||
|
reduction='none',
|
||||||
|
**kwargs)
|
||||||
|
loss = loss[loss_mask].mean()
|
||||||
|
ret = {'loss': loss, 'probe_data': {'prompt': prompt}}
|
||||||
|
return ret
|
||||||
|
|
||||||
|
@torch.no_grad()
|
||||||
|
def forward_test(self,
|
||||||
|
src_image_list=[],
|
||||||
|
src_mask_list=[],
|
||||||
|
edit_id=[],
|
||||||
|
image=None,
|
||||||
|
image_mask=None,
|
||||||
|
prompt=[],
|
||||||
|
sampler='flow_euler',
|
||||||
|
sample_steps=20,
|
||||||
|
seed=2023,
|
||||||
|
guide_scale=3.5,
|
||||||
|
guide_rescale=0.0,
|
||||||
|
show_process=False,
|
||||||
|
log_num=-1,
|
||||||
|
**kwargs):
|
||||||
|
outputs = self.forward_editing(src_image_list=src_image_list,
|
||||||
|
src_mask_list=src_mask_list,
|
||||||
|
edit_id=edit_id,
|
||||||
|
image=image,
|
||||||
|
image_mask=image_mask,
|
||||||
|
prompt=prompt,
|
||||||
|
sampler=sampler,
|
||||||
|
sample_steps=sample_steps,
|
||||||
|
seed=seed,
|
||||||
|
guide_scale=guide_scale,
|
||||||
|
guide_rescale=guide_rescale,
|
||||||
|
show_process=show_process,
|
||||||
|
log_num=log_num,
|
||||||
|
**kwargs)
|
||||||
|
return outputs
|
||||||
|
|
||||||
|
@torch.no_grad()
|
||||||
|
def forward_editing(self,
|
||||||
|
src_image_list=[],
|
||||||
|
src_mask_list=[],
|
||||||
|
edit_id=[],
|
||||||
|
image=None,
|
||||||
|
image_mask=None,
|
||||||
|
prompt=[],
|
||||||
|
sampler='flow_euler',
|
||||||
|
sample_steps=20,
|
||||||
|
seed=2023,
|
||||||
|
guide_scale=3.5,
|
||||||
|
log_num=-1,
|
||||||
|
**kwargs):
|
||||||
|
# gc_seg is unused
|
||||||
|
prompt, image, image_mask, src_image, src_image_mask, edit_id = limit_batch_data(
|
||||||
|
[
|
||||||
|
prompt, image, image_mask, src_image_list, src_mask_list,
|
||||||
|
edit_id
|
||||||
|
], log_num)
|
||||||
|
assert check_list_of_list(src_image) and check_list_of_list(
|
||||||
|
src_image_mask)
|
||||||
|
assert self.cond_stage_model is not None
|
||||||
|
align = kwargs.pop('align', [])
|
||||||
|
prompt_ = [[pp] if isinstance(pp, str) else pp for pp in prompt]
|
||||||
|
if len(align) < 1:
|
||||||
|
align = [0] * len(prompt_)
|
||||||
|
context = getattr(self.cond_stage_model,
|
||||||
|
'encode_list_of_list')(prompt_)
|
||||||
|
guide_scale = guide_scale or self.guide_scale
|
||||||
|
if guide_scale is not None:
|
||||||
|
guide_scale = torch.full((len(prompt), ),
|
||||||
|
guide_scale,
|
||||||
|
device=we.device_id)
|
||||||
|
else:
|
||||||
|
guide_scale = None
|
||||||
|
# image and image_mask
|
||||||
|
seed = seed if seed >= 0 else random.randint(0, 2**32 - 1)
|
||||||
|
if image is not None:
|
||||||
|
if check_list_of_list(image):
|
||||||
|
image = [torch.cat(ix, dim=-1) for ix in image]
|
||||||
|
image_mask = [torch.cat(im, dim=-1) for im in image_mask]
|
||||||
|
noise = [
|
||||||
|
self.noise_sample(1, ix.shape[1], ix.shape[2], seed)
|
||||||
|
for ix in image
|
||||||
|
]
|
||||||
|
else:
|
||||||
|
height, width = kwargs.pop('height'), kwargs.pop('width')
|
||||||
|
noise = [self.noise_sample(1, height, width, seed) for _ in prompt]
|
||||||
|
noise, x_shapes = pack_imagelist_into_tensor(noise)
|
||||||
|
context['x_shapes'] = x_shapes
|
||||||
|
context['align'] = align
|
||||||
|
# process image mask
|
||||||
|
image_mask = to_device(image_mask, strict=False)
|
||||||
|
x_mask = [self.reshape_func(i).squeeze(0) for i in image_mask]
|
||||||
|
context['x_mask'] = x_mask
|
||||||
|
ref_edit_context = self.parse_ref_and_edit(src_image, src_image_mask,
|
||||||
|
context, edit_id)
|
||||||
|
context.update(ref_edit_context)
|
||||||
|
# UNet use input n_prompt
|
||||||
|
# model = self.model_ema if self.use_ema and self.eval_ema else self.model
|
||||||
|
# import pdb;pdb.set_trace()
|
||||||
|
model = self.model
|
||||||
|
embedding_context = model.no_sync if isinstance(model, FullyShardedDataParallel) \
|
||||||
|
else nullcontext
|
||||||
|
with embedding_context():
|
||||||
|
samples = self.diffusion.sample(noise=noise,
|
||||||
|
sampler=sampler,
|
||||||
|
model=self.model,
|
||||||
|
model_kwargs={
|
||||||
|
'cond': context,
|
||||||
|
'guidance': guide_scale,
|
||||||
|
'gc_seg': -1
|
||||||
|
},
|
||||||
|
steps=sample_steps,
|
||||||
|
show_progress=True,
|
||||||
|
guide_scale=guide_scale,
|
||||||
|
return_intermediate=None,
|
||||||
|
**kwargs).float()
|
||||||
|
samples = unpack_tensor_into_imagelist(samples, x_shapes)
|
||||||
|
with torch.autocast(device_type='cuda', dtype=torch.bfloat16):
|
||||||
|
x_samples = self.decode_first_stage(samples)
|
||||||
|
outputs = list()
|
||||||
|
for i in range(len(prompt)):
|
||||||
|
rec_img = torch.clamp((x_samples[i].float() + 1.0) / 2.0,
|
||||||
|
min=0.0,
|
||||||
|
max=1.0)
|
||||||
|
rec_img = rec_img.squeeze(0)
|
||||||
|
edit_imgs, edit_img_masks = [], []
|
||||||
|
if src_image is not None and src_image[i] is not None:
|
||||||
|
if src_image_mask[i] is None:
|
||||||
|
src_image_mask[i] = [None] * len(src_image[i])
|
||||||
|
for edit_img, edit_mask in zip(src_image[i],
|
||||||
|
src_image_mask[i]):
|
||||||
|
edit_img = torch.clamp((edit_img.float() + 1.0) / 2.0,
|
||||||
|
min=0.0,
|
||||||
|
max=1.0)
|
||||||
|
edit_imgs.append(edit_img.squeeze(0))
|
||||||
|
if edit_mask is None:
|
||||||
|
edit_mask = torch.ones_like(edit_img[[0], :, :])
|
||||||
|
edit_img_masks.append(edit_mask)
|
||||||
|
one_tup = {
|
||||||
|
'reconstruct_image': rec_img,
|
||||||
|
'instruction': prompt[i],
|
||||||
|
'edit_image': edit_imgs if len(edit_imgs) > 0 else None,
|
||||||
|
'edit_mask': edit_img_masks if len(edit_imgs) > 0 else None
|
||||||
|
}
|
||||||
|
if image is not None:
|
||||||
|
if image_mask is None:
|
||||||
|
image_mask = [None] * len(image)
|
||||||
|
ori_img = torch.clamp((image[i] + 1.0) / 2.0, min=0.0, max=1.0)
|
||||||
|
one_tup['target_image'] = ori_img.squeeze(0)
|
||||||
|
one_tup['target_mask'] = image_mask[i] if image_mask[
|
||||||
|
i] is not None else torch.ones_like(ori_img[[0], :, :])
|
||||||
|
outputs.append(one_tup)
|
||||||
|
return outputs
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def get_config_template():
|
||||||
|
return dict_to_yaml('MODEL',
|
||||||
|
__class__.__name__,
|
||||||
|
LatentDiffusionACEPlus.para_dict,
|
||||||
|
set_name=True)
|
||||||
@@ -26,19 +26,27 @@ class LatentDiffusionCogVideoX(LatentDiffusion):
|
|||||||
self.use_rotary_positional_embeddings = self.model_config.get('USE_ROTARY_POSITIONAL_EMBEDDINGS', False)
|
self.use_rotary_positional_embeddings = self.model_config.get('USE_ROTARY_POSITIONAL_EMBEDDINGS', False)
|
||||||
self.attention_head_dim = self.model_config.get('ATTENTION_HEAD_DIM', 64)
|
self.attention_head_dim = self.model_config.get('ATTENTION_HEAD_DIM', 64)
|
||||||
self.patch_size = self.model_config.get('PATCH_SIZE', 2)
|
self.patch_size = self.model_config.get('PATCH_SIZE', 2)
|
||||||
self.sample_height = self.first_stage_config.get('SAMPLE_HEIGHT', 480)
|
self.patch_size_t = self.model_config.get('PATCH_SIZE_T', None)
|
||||||
self.sample_width = self.first_stage_config.get('SAMPLE_WIDTH', 720)
|
self.ofs_embed_dim = self.model_config.get('OFS_EMBED_DIM', None)
|
||||||
|
self.sample_height = self.first_stage_config.get('SAMPLE_HEIGHT', 60)
|
||||||
|
self.sample_width = self.first_stage_config.get('SAMPLE_WIDTH', 90)
|
||||||
self.noised_image_dropout = self.cfg.get('NOISED_IMAGE_DROPOUT', 0.05)
|
self.noised_image_dropout = self.cfg.get('NOISED_IMAGE_DROPOUT', 0.05)
|
||||||
|
self.invert_scale_latents = self.cfg.get('INVERT_SCALE_LATENTS', False)
|
||||||
|
|
||||||
def construct_network(self):
|
def construct_network(self):
|
||||||
super().construct_network()
|
super().construct_network()
|
||||||
self.model = self.model.to(getattr(torch, self.model_config.DTYPE))
|
self.model = self.model.to(getattr(torch, self.model_config.DTYPE))
|
||||||
|
self.first_stage_model = self.first_stage_model.to(getattr(torch, self.first_stage_config.DTYPE))
|
||||||
|
|
||||||
@torch.no_grad()
|
@torch.no_grad()
|
||||||
def encode_first_stage(self, x, **kwargs):
|
def encode_first_stage(self, x, **kwargs):
|
||||||
if isinstance(x, list):
|
if isinstance(x, list):
|
||||||
x = torch.stack(x, dim=0) # [B, C, F, H, W]
|
x = torch.stack(x, dim=0) # [B, C, F, H, W]
|
||||||
latents = self.scaling_factor_image * self.first_stage_model.encode(x).sample()
|
image_latents = self.first_stage_model.encode(x).sample()
|
||||||
|
if not self.invert_scale_latents:
|
||||||
|
latents = self.scaling_factor_image * image_latents
|
||||||
|
else:
|
||||||
|
latents = 1 / self.scaling_factor_image * image_latents
|
||||||
return latents
|
return latents
|
||||||
|
|
||||||
@torch.no_grad()
|
@torch.no_grad()
|
||||||
@@ -78,18 +86,36 @@ class LatentDiffusionCogVideoX(LatentDiffusion):
|
|||||||
) -> Tuple[torch.Tensor, torch.Tensor]:
|
) -> Tuple[torch.Tensor, torch.Tensor]:
|
||||||
grid_height = height // (self.scale_factor_spatial * self.patch_size)
|
grid_height = height // (self.scale_factor_spatial * self.patch_size)
|
||||||
grid_width = width // (self.scale_factor_spatial * self.patch_size)
|
grid_width = width // (self.scale_factor_spatial * self.patch_size)
|
||||||
base_size_width = self.sample_width // (self.scale_factor_spatial * self.patch_size)
|
|
||||||
base_size_height = self.sample_height // (self.scale_factor_spatial * self.patch_size)
|
|
||||||
|
|
||||||
grid_crops_coords = get_resize_crop_region_for_grid(
|
p = self.patch_size
|
||||||
(grid_height, grid_width), base_size_width, base_size_height
|
p_t = self.patch_size_t
|
||||||
)
|
|
||||||
freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
|
base_size_width = self.sample_width // p
|
||||||
embed_dim=self.attention_head_dim,
|
base_size_height = self.sample_height // p
|
||||||
crops_coords=grid_crops_coords,
|
|
||||||
grid_size=(grid_height, grid_width),
|
if p_t is None:
|
||||||
temporal_size=num_frames,
|
# CogVideoX 1.0
|
||||||
)
|
grid_crops_coords = get_resize_crop_region_for_grid(
|
||||||
|
(grid_height, grid_width), base_size_width, base_size_height
|
||||||
|
)
|
||||||
|
freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
|
||||||
|
embed_dim=self.attention_head_dim,
|
||||||
|
crops_coords=grid_crops_coords,
|
||||||
|
grid_size=(grid_height, grid_width),
|
||||||
|
temporal_size=num_frames,
|
||||||
|
)
|
||||||
|
else:
|
||||||
|
# CogVideoX 1.5
|
||||||
|
base_num_frames = (num_frames + p_t - 1) // p_t
|
||||||
|
|
||||||
|
freqs_cos, freqs_sin = get_3d_rotary_pos_embed(
|
||||||
|
embed_dim=self.attention_head_dim,
|
||||||
|
crops_coords=None,
|
||||||
|
grid_size=(grid_height, grid_width),
|
||||||
|
temporal_size=base_num_frames,
|
||||||
|
grid_type="slice",
|
||||||
|
max_size=(base_size_height, base_size_width),
|
||||||
|
)
|
||||||
|
|
||||||
freqs_cos = freqs_cos.to(device=device)
|
freqs_cos = freqs_cos.to(device=device)
|
||||||
freqs_sin = freqs_sin.to(device=device)
|
freqs_sin = freqs_sin.to(device=device)
|
||||||
@@ -121,19 +147,21 @@ class LatentDiffusionCogVideoX(LatentDiffusion):
|
|||||||
else:
|
else:
|
||||||
image_latent = None
|
image_latent = None
|
||||||
|
|
||||||
height, width = image_size
|
height, width = image_size[0] if isinstance(image_size, list) and all(isinstance(elem, list) for elem in image_size) else image_size
|
||||||
image_rotary_emb = (
|
image_rotary_emb = (
|
||||||
self._prepare_rotary_positional_embeddings(height, width, noise.size(1), we.device_id)
|
self._prepare_rotary_positional_embeddings(height=height, width=width, num_frames=noise.size(1), device=we.device_id)
|
||||||
if self.use_rotary_positional_embeddings
|
if self.use_rotary_positional_embeddings
|
||||||
else None
|
else None
|
||||||
)
|
)
|
||||||
|
ofs_emb = None if self.ofs_embed_dim is None else image_latent.new_full((1,), fill_value=2.0)
|
||||||
|
|
||||||
loss = self.diffusion.loss(x_0=x_start,
|
loss = self.diffusion.loss(x_0=x_start,
|
||||||
t=t,
|
t=t,
|
||||||
model=self.model,
|
model=self.model,
|
||||||
model_kwargs={"cond": cont,
|
model_kwargs={"cond": cont,
|
||||||
'image_latent': image_latent,
|
'image_latent': image_latent,
|
||||||
'image_rotary_emb': image_rotary_emb},
|
'image_rotary_emb': image_rotary_emb,
|
||||||
|
'ofs': ofs_emb},
|
||||||
noise=noise,
|
noise=noise,
|
||||||
**kwargs)
|
**kwargs)
|
||||||
loss = loss.mean()
|
loss = loss.mean()
|
||||||
@@ -160,6 +188,7 @@ class LatentDiffusionCogVideoX(LatentDiffusion):
|
|||||||
image_size = [480, 720]
|
image_size = [480, 720]
|
||||||
seed = seed if seed >= 0 else random.randint(0, 2**32 - 1)
|
seed = seed if seed >= 0 else random.randint(0, 2**32 - 1)
|
||||||
generator = torch.Generator().manual_seed(seed)
|
generator = torch.Generator().manual_seed(seed)
|
||||||
|
# generator = torch.Generator(we.device_id).manual_seed(seed)
|
||||||
prompt = [prompt] if isinstance(prompt, str) else prompt
|
prompt = [prompt] if isinstance(prompt, str) else prompt
|
||||||
num_samples = len(prompt)
|
num_samples = len(prompt)
|
||||||
n_prompt = default(n_prompt, [self.default_n_prompt] * len(prompt))
|
n_prompt = default(n_prompt, [self.default_n_prompt] * len(prompt))
|
||||||
@@ -169,14 +198,21 @@ class LatentDiffusionCogVideoX(LatentDiffusion):
|
|||||||
cont = getattr(self.cond_stage_model, 'encode')(prompt, return_mask=False, use_mask=False)
|
cont = getattr(self.cond_stage_model, 'encode')(prompt, return_mask=False, use_mask=False)
|
||||||
null_cont = getattr(self.cond_stage_model, 'encode')(n_prompt, return_mask=False, use_mask=False)
|
null_cont = getattr(self.cond_stage_model, 'encode')(n_prompt, return_mask=False, use_mask=False)
|
||||||
|
|
||||||
height, width = image_size
|
height, width = image_size[0] if isinstance(image_size, list) and all(isinstance(elem, list) for elem in image_size) else image_size
|
||||||
|
latent_frames = (num_frames - 1) // self.scale_factor_temporal + 1
|
||||||
|
additional_frames = 0
|
||||||
|
if self.patch_size_t is not None and latent_frames % self.patch_size_t != 0:
|
||||||
|
additional_frames = self.patch_size_t - latent_frames % self.patch_size_t
|
||||||
|
num_frames += additional_frames * self.scale_factor_temporal
|
||||||
noise = self.noise_sample(num_samples, num_frames, height, width, generator)
|
noise = self.noise_sample(num_samples, num_frames, height, width, generator)
|
||||||
image_rotary_emb = (
|
image_rotary_emb = (
|
||||||
self._prepare_rotary_positional_embeddings(height, width, noise.size(1), we.device_id)
|
self._prepare_rotary_positional_embeddings(height, width, noise.size(1), we.device_id)
|
||||||
if self.use_rotary_positional_embeddings
|
if self.use_rotary_positional_embeddings
|
||||||
else None
|
else None
|
||||||
)
|
)
|
||||||
|
|
||||||
image_latent, image = self.get_image_latent(image, video, noise) if image is not None else (None, None)
|
image_latent, image = self.get_image_latent(image, video, noise) if image is not None else (None, None)
|
||||||
|
ofs_emb = None if self.ofs_embed_dim is None else image_latent.new_full((1,), fill_value=2.0)
|
||||||
|
|
||||||
samples = self.diffusion.sample(noise=noise,
|
samples = self.diffusion.sample(noise=noise,
|
||||||
sampler=sampler,
|
sampler=sampler,
|
||||||
@@ -185,19 +221,21 @@ class LatentDiffusionCogVideoX(LatentDiffusion):
|
|||||||
'cond': cont,
|
'cond': cont,
|
||||||
'image_latent': image_latent,
|
'image_latent': image_latent,
|
||||||
'image_rotary_emb': image_rotary_emb,
|
'image_rotary_emb': image_rotary_emb,
|
||||||
|
'ofs': ofs_emb
|
||||||
}, {
|
}, {
|
||||||
'cond': null_cont,
|
'cond': null_cont,
|
||||||
'image_latent': image_latent,
|
'image_latent': image_latent,
|
||||||
'image_rotary_emb': image_rotary_emb,
|
'image_rotary_emb': image_rotary_emb,
|
||||||
|
'ofs': ofs_emb
|
||||||
}],
|
}],
|
||||||
steps=sample_steps,
|
steps=sample_steps,
|
||||||
show_progress=True,
|
show_progress=True,
|
||||||
use_dynamic_cfg=True,
|
|
||||||
guide_scale=guide_scale,
|
guide_scale=guide_scale,
|
||||||
guide_rescale=guide_rescale,
|
guide_rescale=guide_rescale,
|
||||||
return_intermediate=None,
|
return_intermediate=None,
|
||||||
**kwargs).float()
|
**kwargs).float()
|
||||||
|
|
||||||
|
samples = samples[:, additional_frames:]
|
||||||
x_frames = self.decode_first_stage(samples).float()
|
x_frames = self.decode_first_stage(samples).float()
|
||||||
|
|
||||||
outputs = []
|
outputs = []
|
||||||
|
|||||||
@@ -14,16 +14,13 @@ from scepter.modules.model.utils.basic_utils import disabled_train, check_list_o
|
|||||||
from scepter.modules.utils.config import dict_to_yaml
|
from scepter.modules.utils.config import dict_to_yaml
|
||||||
from scepter.modules.utils.distribute import we
|
from scepter.modules.utils.distribute import we
|
||||||
from scepter.modules.model.utils.basic_utils import count_params
|
from scepter.modules.model.utils.basic_utils import count_params
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
@MODELS.register_class()
|
@MODELS.register_class()
|
||||||
class LatentDiffusionFlux(LatentDiffusion):
|
class LatentDiffusionFlux(LatentDiffusion):
|
||||||
para_dict = LatentDiffusion.para_dict
|
para_dict = LatentDiffusion.para_dict
|
||||||
|
|
||||||
def __init__(self, cfg, logger=None):
|
def __init__(self, cfg, logger=None):
|
||||||
super().__init__(cfg, logger=logger)
|
super().__init__(cfg, logger=logger)
|
||||||
self.guide_scale = cfg.get('GUIDE_SCALE', 3.5)
|
self.guide_scale = cfg.get('GUIDE_SCALE', 1.0)
|
||||||
|
|
||||||
def init_params(self):
|
def init_params(self):
|
||||||
self.parameterization = self.cfg.get('PARAMETERIZATION', 'rf')
|
self.parameterization = self.cfg.get('PARAMETERIZATION', 'rf')
|
||||||
@@ -271,7 +268,7 @@ class LatentDiffusionFluxMR(LatentDiffusionFlux):
|
|||||||
guide_scale=3.5,
|
guide_scale=3.5,
|
||||||
show_process=True,
|
show_process=True,
|
||||||
x = None,
|
x = None,
|
||||||
reverse_scale = 0.,
|
reverse_scale = -1.,
|
||||||
**kwargs
|
**kwargs
|
||||||
):
|
):
|
||||||
noise, x_shapes = pack_imagelist_into_tensor(noise)
|
noise, x_shapes = pack_imagelist_into_tensor(noise)
|
||||||
@@ -377,9 +374,167 @@ class LatentDiffusionFluxMR(LatentDiffusionFlux):
|
|||||||
zu = zu[0]
|
zu = zu[0]
|
||||||
return zu
|
return zu
|
||||||
|
|
||||||
z = [run_one_image(u.unsqueeze(0) if u.dim == 3 else u) for u in x]
|
z = [run_one_image(u.unsqueeze(0) if u.dim() == 3 else u) for u in x]
|
||||||
return z
|
return z
|
||||||
|
|
||||||
@torch.no_grad()
|
@torch.no_grad()
|
||||||
def decode_first_stage(self, z):
|
def decode_first_stage(self, z):
|
||||||
return [self.first_stage_model.decode(zu) for zu in z]
|
return [self.first_stage_model.decode(zu) for zu in z]
|
||||||
|
|
||||||
|
@MODELS.register_class()
|
||||||
|
class LatentDiffusionFluxMRRedux(LatentDiffusionFluxMR):
|
||||||
|
para_dict = {
|
||||||
|
}
|
||||||
|
para_dict.update(LatentDiffusionFluxMR.para_dict)
|
||||||
|
|
||||||
|
def init_params(self):
|
||||||
|
super().init_params()
|
||||||
|
self.redux_adapter_cfg = self.cfg.get("REDUX_ADAPTER", None)
|
||||||
|
|
||||||
|
|
||||||
|
def construct_network(self):
|
||||||
|
super().construct_network()
|
||||||
|
if self.redux_adapter_cfg is not None:
|
||||||
|
self.redux_adapter = EMBEDDERS.build(self.redux_adapter_cfg, logger=self.logger).eval().requires_grad_(False)
|
||||||
|
|
||||||
|
def forward_train(self,
|
||||||
|
image=None,
|
||||||
|
noise=None,
|
||||||
|
prompt=[],
|
||||||
|
**kwargs):
|
||||||
|
if check_list_of_list(prompt):
|
||||||
|
prompt = [pp[0] for pp in prompt]
|
||||||
|
assert self.cond_stage_model is not None
|
||||||
|
gc_seg = kwargs.pop("gc_seg", [])
|
||||||
|
gc_seg = int(gc_seg[0]) if len(gc_seg) > 0 else 0
|
||||||
|
context = getattr(self.cond_stage_model, 'encode')(prompt)
|
||||||
|
|
||||||
|
image = to_device(image)
|
||||||
|
x_start = self.encode_first_stage(image, **kwargs)
|
||||||
|
loss_mask, _ = pack_imagelist_into_tensor(tuple(torch.ones_like(ix, dtype=torch.bool, device=ix.device) for ix in x_start))
|
||||||
|
x_start, x_shapes = pack_imagelist_into_tensor(x_start)
|
||||||
|
context['x_shapes'] = x_shapes
|
||||||
|
guide_scale = self.guide_scale
|
||||||
|
if guide_scale is not None:
|
||||||
|
guide_scale = torch.full((x_start.shape[0],), guide_scale, device=x_start.device, dtype=x_start.dtype)
|
||||||
|
else:
|
||||||
|
guide_scale = None
|
||||||
|
loss = self.diffusion.loss(x_0=x_start,
|
||||||
|
model=self.model,
|
||||||
|
model_kwargs={"cond": context,
|
||||||
|
"gc_seg": gc_seg,
|
||||||
|
"guidance": guide_scale},
|
||||||
|
noise=None,
|
||||||
|
reduction='none',
|
||||||
|
**kwargs)
|
||||||
|
loss = loss[loss_mask].mean()
|
||||||
|
ret = {'loss': loss, 'probe_data': {'prompt': prompt}}
|
||||||
|
return ret
|
||||||
|
|
||||||
|
@torch.no_grad()
|
||||||
|
def forward_sample(self,
|
||||||
|
noise = None,
|
||||||
|
prompt=None,
|
||||||
|
sampler='flow_euler',
|
||||||
|
sample_steps=20,
|
||||||
|
guide_scale=3.5,
|
||||||
|
show_process=True,
|
||||||
|
x = None,
|
||||||
|
reverse_scale = -1.,
|
||||||
|
**kwargs
|
||||||
|
):
|
||||||
|
noise, x_shapes = pack_imagelist_into_tensor(noise)
|
||||||
|
if x is not None:
|
||||||
|
x, _ = pack_imagelist_into_tensor(x)
|
||||||
|
context = getattr(self.cond_stage_model, 'encode')(prompt)
|
||||||
|
context["x_shapes"] = x_shapes
|
||||||
|
guide_scale = guide_scale or self.guide_scale
|
||||||
|
if guide_scale is not None:
|
||||||
|
guide_scale = torch.full((noise.shape[0],), guide_scale, device=noise.device, dtype=noise.dtype)
|
||||||
|
else:
|
||||||
|
guide_scale = None
|
||||||
|
# UNet use input n_prompt
|
||||||
|
model = self.model_ema if self.use_ema and self.eval_ema else self.model
|
||||||
|
embedding_context = model.no_sync if isinstance(model, torch.distributed.fsdp.FullyShardedDataParallel) \
|
||||||
|
else nullcontext
|
||||||
|
with embedding_context():
|
||||||
|
x_samples = self.diffusion.sample(
|
||||||
|
noise=noise,
|
||||||
|
sampler=sampler,
|
||||||
|
model=self.model,
|
||||||
|
model_kwargs={"cond": context, "guidance": guide_scale, "gc_seg": -1},
|
||||||
|
steps=sample_steps,
|
||||||
|
show_progress=True,
|
||||||
|
guide_scale=guide_scale,
|
||||||
|
return_intermediate=None,
|
||||||
|
reverse_scale = reverse_scale,
|
||||||
|
x = x,
|
||||||
|
**kwargs).float()
|
||||||
|
x_samples = unpack_tensor_into_imagelist(x_samples, x_shapes)
|
||||||
|
with torch.autocast(device_type="cuda", dtype=torch.bfloat16):
|
||||||
|
x_samples = self.decode_first_stage(x_samples)
|
||||||
|
return x_samples
|
||||||
|
@torch.no_grad()
|
||||||
|
def forward_test(self,
|
||||||
|
image=None,
|
||||||
|
prompt=[],
|
||||||
|
sampler='flow_euler',
|
||||||
|
sample_steps=20,
|
||||||
|
seed=2023,
|
||||||
|
guide_scale=3.5,
|
||||||
|
guide_rescale=0.0,
|
||||||
|
show_process=True,
|
||||||
|
log_num = -1,
|
||||||
|
**kwargs):
|
||||||
|
|
||||||
|
if check_list_of_list(prompt):
|
||||||
|
prompt = [pp[0] for pp in prompt]
|
||||||
|
assert self.cond_stage_model is not None
|
||||||
|
# gc_seg is unused
|
||||||
|
prompt, image = limit_batch_data([prompt, image], log_num)
|
||||||
|
seed = seed if seed >= 0 else random.randint(0, 2**32 - 1)
|
||||||
|
|
||||||
|
if 'index' in kwargs:
|
||||||
|
kwargs.pop('index')
|
||||||
|
if image is not None:
|
||||||
|
noise = [self.noise_sample(1, ix.shape[1], ix.shape[2], seed) for ix in image]
|
||||||
|
else:
|
||||||
|
image_size = None
|
||||||
|
if 'meta' in kwargs:
|
||||||
|
meta = kwargs.pop('meta')
|
||||||
|
if 'image_size' in meta:
|
||||||
|
h = int(meta['image_size'][0][0])
|
||||||
|
w = int(meta['image_size'][1][0])
|
||||||
|
image_size = [h, w]
|
||||||
|
if 'image_size' in kwargs:
|
||||||
|
image_size = kwargs.pop('image_size')
|
||||||
|
if isinstance(image_size, numbers.Number):
|
||||||
|
image_size = [image_size, image_size]
|
||||||
|
if image_size is None:
|
||||||
|
image_size = [1024, 1024]
|
||||||
|
height, width = image_size
|
||||||
|
noise = [self.noise_sample(1, height, width, seed) for _ in prompt]
|
||||||
|
|
||||||
|
x_samples = self.forward_sample(
|
||||||
|
prompt=prompt,
|
||||||
|
sampler=sampler,
|
||||||
|
sample_steps=sample_steps,
|
||||||
|
guide_scale=guide_scale,
|
||||||
|
show_process=show_process,
|
||||||
|
noise=noise,
|
||||||
|
)
|
||||||
|
|
||||||
|
|
||||||
|
outputs = list()
|
||||||
|
for i in range(len(prompt)):
|
||||||
|
rec_img = torch.clamp((x_samples[i].float() + 1.0) / 2.0, min=0.0, max=1.0)
|
||||||
|
rec_img = rec_img.squeeze(0)
|
||||||
|
one_tup = {'prompt': prompt[i], 'n_prompt': '', 'image': rec_img}
|
||||||
|
outputs.append(one_tup)
|
||||||
|
return outputs
|
||||||
|
@staticmethod
|
||||||
|
def get_config_template():
|
||||||
|
return dict_to_yaml('MODEL',
|
||||||
|
__class__.__name__,
|
||||||
|
LatentDiffusionFluxMR.para_dict,
|
||||||
|
set_name=True)
|
||||||
|
|||||||
@@ -80,7 +80,7 @@ class LatentDiffusionXL(LatentDiffusion):
|
|||||||
from safetensors.torch import load_file as load_safetensors
|
from safetensors.torch import load_file as load_safetensors
|
||||||
sd = load_safetensors(path)
|
sd = load_safetensors(path)
|
||||||
else:
|
else:
|
||||||
sd = torch.load(path, map_location='cpu')
|
sd = torch.load(path, map_location='cpu', weights_only=True)
|
||||||
new_sd = OrderedDict()
|
new_sd = OrderedDict()
|
||||||
for k, v in sd.items():
|
for k, v in sd.items():
|
||||||
ignored = False
|
ignored = False
|
||||||
|
|||||||
@@ -19,7 +19,7 @@ def build_model(cfg, registry, logger=None, *args, **kwargs):
|
|||||||
raise TypeError('Pretrain parameter must be a string or list')
|
raise TypeError('Pretrain parameter must be a string or list')
|
||||||
else:
|
else:
|
||||||
pretrain_cfg = None
|
pretrain_cfg = None
|
||||||
|
device = cfg.get("DEVICE", None)
|
||||||
model = build_from_config(cfg, registry, logger=logger, *args, **kwargs)
|
model = build_from_config(cfg, registry, logger=logger, *args, **kwargs)
|
||||||
if pretrain_cfg is not None:
|
if pretrain_cfg is not None:
|
||||||
if hasattr(model, 'load_pretrained_model'):
|
if hasattr(model, 'load_pretrained_model'):
|
||||||
@@ -49,7 +49,7 @@ def build_diffusion_sampler(cfg, registry, logger=None, *args, **kwargs):
|
|||||||
|
|
||||||
|
|
||||||
MODELS = Registry('MODELS', build_func=build_model)
|
MODELS = Registry('MODELS', build_func=build_model)
|
||||||
TOKENIZERS = Registry('TOKENIZER', build_func=build_model)
|
TOKENIZERS = Registry('TOKENIZERS', build_func=build_model)
|
||||||
EMBEDDERS = Registry('EMBEDDERS', build_func=build_model)
|
EMBEDDERS = Registry('EMBEDDERS', build_func=build_model)
|
||||||
BACKBONES = Registry('BACKBONES', build_func=build_model)
|
BACKBONES = Registry('BACKBONES', build_func=build_model)
|
||||||
NECKS = Registry('NECKS', build_func=build_model)
|
NECKS = Registry('NECKS', build_func=build_model)
|
||||||
|
|||||||
@@ -1,6 +1,25 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.model.tokenizer.base_tokenizer import BaseTokenizer
|
from typing import TYPE_CHECKING
|
||||||
from scepter.modules.model.tokenizer.tokenizer import (ClipTokenizer,
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
HuggingfaceTokenizer,
|
|
||||||
OpenClipTokenizer)
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.model.tokenizer.base_tokenizer import BaseTokenizer
|
||||||
|
from scepter.modules.model.tokenizer.tokenizer import (ClipTokenizer,
|
||||||
|
HuggingfaceTokenizer,
|
||||||
|
OpenClipTokenizer)
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'base_tokenizer': ['BaseTokenizer'],
|
||||||
|
'tokenizer': ['ClipTokenizer', 'HuggingfaceTokenizer', 'OpenClipTokenizer']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -152,9 +152,9 @@ def heavy_clean(text):
|
|||||||
text = re.sub(r'[\"\']{2,}', r'"', text) # """AUSVERKAUFT"""
|
text = re.sub(r'[\"\']{2,}', r'"', text) # """AUSVERKAUFT"""
|
||||||
text = re.sub(r'[\.]{2,}', r' ', text) # """AUSVERKAUFT"""
|
text = re.sub(r'[\.]{2,}', r' ', text) # """AUSVERKAUFT"""
|
||||||
text = re.sub(
|
text = re.sub(
|
||||||
re.compile(r'[' + '#®•©™&@·º½¾¿¡§~' + '\)' + '\(' + '\]' + # noqa
|
re.compile(r'[' + '#®•©™&@·º½¾¿¡§~' + r'\)' + r'\(' + r'\]' + # noqa
|
||||||
'\[' + # noqa
|
r'\[' + # noqa
|
||||||
'\}' + '\{' + '\|' + '\\' + '\/' + '\*' + # noqa
|
r'\}' + r'\{' + r'\|' + '\\' + r'\/' + r'\*' + # noqa
|
||||||
r']{1,}'), # noqa
|
r']{1,}'), # noqa
|
||||||
r' ',
|
r' ',
|
||||||
text) # ***AUSVERKAUFT***, #AUSVERKAUFT
|
text) # ***AUSVERKAUFT***, #AUSVERKAUFT
|
||||||
|
|||||||
@@ -1,5 +1,25 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.model.tuner import sce
|
from typing import TYPE_CHECKING
|
||||||
from scepter.modules.model.tuner.swift_tuner import (SwiftPart, SwiftAdapter, SwiftFull,
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
SwiftLoRA, SwiftSCETuning)
|
|
||||||
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.model.tuner import sce
|
||||||
|
from scepter.modules.model.tuner.swift_tuner import (SwiftPart, SwiftAdapter, SwiftFull,
|
||||||
|
SwiftLoRA, SwiftSCETuning)
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'tuner': ['sce'],
|
||||||
|
'swift_tuner': ['SwiftPart', 'SwiftAdapter', 'SwiftFull',
|
||||||
|
'SwiftLoRA', 'SwiftSCETuning']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -1,4 +1,23 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.model.tuner.sce.scetuning import CSCTuners, SCTuner
|
from typing import TYPE_CHECKING
|
||||||
from scepter.modules.model.tuner.sce.scetuning_component import SCEAdapter
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.model.tuner.sce.scetuning import CSCTuners, SCTuner
|
||||||
|
from scepter.modules.model.tuner.sce.scetuning_component import SCEAdapter
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'scetuning': ['CSCTuners', 'SCTuner'],
|
||||||
|
'scetuning_component': ['SCEAdapter']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -153,7 +153,7 @@ class CSCTuners(BaseTuner):
|
|||||||
|
|
||||||
def init_from_ckpt(self, path):
|
def init_from_ckpt(self, path):
|
||||||
model_new = OrderedDict()
|
model_new = OrderedDict()
|
||||||
model = torch.load(path, map_location='cpu')
|
model = torch.load(path, map_location='cpu', weights_only=True)
|
||||||
for k, v in model.items():
|
for k, v in model.items():
|
||||||
if k.startswith('model.'):
|
if k.startswith('model.'):
|
||||||
k = k[len('model.'):]
|
k = k[len('model.'):]
|
||||||
|
|||||||
@@ -79,6 +79,7 @@ class SwiftLoRA():
|
|||||||
lora_alpha=cfg.LORA_ALPHA,
|
lora_alpha=cfg.LORA_ALPHA,
|
||||||
lora_dropout=cfg.LORA_DROPOUT,
|
lora_dropout=cfg.LORA_DROPOUT,
|
||||||
bias=cfg.BIAS,
|
bias=cfg.BIAS,
|
||||||
|
use_dora=cfg.get('USE_DORA', False),
|
||||||
target_modules=cfg.TARGET_MODULES)
|
target_modules=cfg.TARGET_MODULES)
|
||||||
|
|
||||||
def __call__(self, *args, **kwargs):
|
def __call__(self, *args, **kwargs):
|
||||||
|
|||||||
@@ -1,4 +1,21 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
from typing import TYPE_CHECKING
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
from scepter.modules.opt import lr_schedulers, optimizers
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.opt import lr_schedulers, optimizers
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'opt': ['lr_schedulers', 'optimizers']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -1,7 +1,29 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
from typing import TYPE_CHECKING
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
from scepter.modules.opt.lr_schedulers.define_schedulers import LinoPolyLR
|
|
||||||
from scepter.modules.opt.lr_schedulers.official_schedulers import * # noqa
|
if TYPE_CHECKING:
|
||||||
from scepter.modules.opt.lr_schedulers.warmup import (StepAnnealingLR,
|
from scepter.modules.opt.lr_schedulers.define_schedulers import LinoPolyLR
|
||||||
WarmupToConstantLR)
|
from scepter.modules.opt.lr_schedulers.official_schedulers import * # noqa
|
||||||
|
from scepter.modules.opt.lr_schedulers.warmup import (StepAnnealingLR,
|
||||||
|
WarmupToConstantLR)
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'define_schedulers': ['LinoPolyLR'],
|
||||||
|
'official_schedulers': ['StepLR', 'CyclicLR', 'LambdaLR', 'MultiStepLR',
|
||||||
|
'ExponentialLR', 'CosineAnnealingLR',
|
||||||
|
'CosineAnnealingWarmRestarts', 'ReduceLROnPlateau'],
|
||||||
|
'warmup': ['StepAnnealingLR', 'WarmupToConstantLR'],
|
||||||
|
'registry': ['LR_SCHEDULERS']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -18,8 +18,12 @@ def build_lr_scheduler(cfg, registry, logger=None, *args, **kwargs):
|
|||||||
cfg = deep_copy(cfg)
|
cfg = deep_copy(cfg)
|
||||||
assert kwargs is not None and 'optimizer' in kwargs
|
assert kwargs is not None and 'optimizer' in kwargs
|
||||||
optimizer = kwargs['optimizer']
|
optimizer = kwargs['optimizer']
|
||||||
|
|
||||||
req_type = cfg.get('NAME')
|
req_type = cfg.get('NAME')
|
||||||
|
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
sig = (registry.name.upper(), req_type)
|
||||||
|
LazyImportModule.import_module(sig)
|
||||||
|
|
||||||
if isinstance(req_type, str):
|
if isinstance(req_type, str):
|
||||||
req_type_entry = registry.get(req_type)
|
req_type_entry = registry.get(req_type)
|
||||||
if req_type_entry is None:
|
if req_type_entry is None:
|
||||||
|
|||||||
@@ -1,7 +1,27 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
from typing import TYPE_CHECKING
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
from scepter.modules.opt.optimizers.official_optimizers import (
|
|
||||||
ASGD, LBFGS, SGD, Adadelta, Adagrad, Adam, Adamax, AdamW, RMSprop, Rprop,
|
if TYPE_CHECKING:
|
||||||
SparseAdam)
|
from scepter.modules.opt.optimizers.official_optimizers import (
|
||||||
from scepter.modules.opt.optimizers.registry import OPTIMIZERS
|
ASGD, LBFGS, SGD, Adadelta, Adagrad, Adam, Adamax, AdamW, RMSprop, Rprop,
|
||||||
|
SparseAdam)
|
||||||
|
from scepter.modules.opt.optimizers.registry import OPTIMIZERS
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'official_optimizers': ['ASGD', 'LBFGS', 'SGD', 'Adadelta',
|
||||||
|
'Adagrad', 'Adam', 'Adamax', 'AdamW',
|
||||||
|
'RMSprop', 'Rprop', 'SparseAdam'],
|
||||||
|
'registry': ['OPTIMIZERS']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -19,8 +19,12 @@ def build_optimizer(cfg, registry, logger=None, *args, **kwargs):
|
|||||||
parameters = kwargs['parameters']
|
parameters = kwargs['parameters']
|
||||||
|
|
||||||
cfg = deep_copy(cfg)
|
cfg = deep_copy(cfg)
|
||||||
|
|
||||||
req_type = cfg.get('NAME')
|
req_type = cfg.get('NAME')
|
||||||
|
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
sig = (registry.name.upper(), req_type)
|
||||||
|
LazyImportModule.import_module(sig)
|
||||||
|
|
||||||
if isinstance(req_type, str):
|
if isinstance(req_type, str):
|
||||||
req_type_entry = registry.get(req_type)
|
req_type_entry = registry.get(req_type)
|
||||||
if req_type_entry is None:
|
if req_type_entry is None:
|
||||||
|
|||||||
@@ -1,8 +1,33 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.solver import hooks
|
from typing import TYPE_CHECKING
|
||||||
from scepter.modules.solver.base_solver import BaseSolver
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
from scepter.modules.solver.diffusion_solver import LatentDiffusionSolver
|
|
||||||
from scepter.modules.solver.train_val_solver import TrainValSolver
|
|
||||||
from scepter.modules.solver.ace_solver import ACESolver
|
if TYPE_CHECKING:
|
||||||
from scepter.modules.solver.diffusion_video_solver import LatentDiffusionVideoSolver
|
from scepter.modules.solver import hooks
|
||||||
|
from scepter.modules.solver.base_solver import BaseSolver
|
||||||
|
from scepter.modules.solver.diffusion_solver import LatentDiffusionSolver
|
||||||
|
from scepter.modules.solver.train_val_solver import TrainValSolver
|
||||||
|
from scepter.modules.solver.ace_solver import ACESolver
|
||||||
|
from scepter.modules.solver.ace_plus_solver import ACEPlusSolver
|
||||||
|
from scepter.modules.solver.diffusion_video_solver import LatentDiffusionVideoSolver
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'solver': ['hooks'],
|
||||||
|
'base_solver': ['BaseSolver'],
|
||||||
|
'diffusion_solver': ['LatentDiffusionSolver'],
|
||||||
|
'train_val_solver': ['TrainValSolver'],
|
||||||
|
'ace_solver': ['ACESolver'],
|
||||||
|
'ace_plus_solver': ['ACEPlusSolver'],
|
||||||
|
'diffusion_video_solver': ['LatentDiffusionVideoSolver']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -0,0 +1,164 @@
|
|||||||
|
# -*- coding: utf-8 -*-
|
||||||
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
import numpy as np
|
||||||
|
import torch
|
||||||
|
from scepter.modules.solver import LatentDiffusionSolver
|
||||||
|
from scepter.modules.solver.registry import SOLVERS
|
||||||
|
from scepter.modules.utils.data import transfer_data_to_cuda
|
||||||
|
from scepter.modules.utils.distribute import we
|
||||||
|
from scepter.modules.utils.probe import ProbeData
|
||||||
|
from tqdm import tqdm
|
||||||
|
@SOLVERS.register_class()
|
||||||
|
class ACEPlusSolver(LatentDiffusionSolver):
|
||||||
|
def __init__(self, cfg, logger=None):
|
||||||
|
super().__init__(cfg, logger=logger)
|
||||||
|
self.probe_prompt = cfg.get("PROBE_PROMPT", None)
|
||||||
|
self.probe_hw = cfg.get("PROBE_HW", [])
|
||||||
|
@torch.no_grad()
|
||||||
|
def run_eval(self):
|
||||||
|
self.eval_mode()
|
||||||
|
self.before_all_iter(self.hooks_dict[self._mode])
|
||||||
|
all_results = []
|
||||||
|
for batch_idx, batch_data in tqdm(
|
||||||
|
enumerate(self.datas[self._mode].dataloader)):
|
||||||
|
self.before_iter(self.hooks_dict[self._mode])
|
||||||
|
if self.sample_args:
|
||||||
|
batch_data.update(self.sample_args.get_lowercase_dict())
|
||||||
|
with torch.autocast(device_type='cuda',
|
||||||
|
enabled=self.use_amp,
|
||||||
|
dtype=self.dtype):
|
||||||
|
results = self.run_step_eval(transfer_data_to_cuda(batch_data),
|
||||||
|
batch_idx,
|
||||||
|
step=self.total_iter,
|
||||||
|
rank=we.rank)
|
||||||
|
all_results.extend(results)
|
||||||
|
self.after_iter(self.hooks_dict[self._mode])
|
||||||
|
log_data, log_label = self.save_results(all_results)
|
||||||
|
self.register_probe({'eval_label': log_label})
|
||||||
|
self.register_probe({
|
||||||
|
'eval_image':
|
||||||
|
ProbeData(log_data,
|
||||||
|
is_image=True,
|
||||||
|
build_html=True,
|
||||||
|
build_label=log_label)
|
||||||
|
})
|
||||||
|
self.after_all_iter(self.hooks_dict[self._mode])
|
||||||
|
|
||||||
|
@torch.no_grad()
|
||||||
|
def run_test(self):
|
||||||
|
self.test_mode()
|
||||||
|
self.before_all_iter(self.hooks_dict[self._mode])
|
||||||
|
all_results = []
|
||||||
|
for batch_idx, batch_data in tqdm(
|
||||||
|
enumerate(self.datas[self._mode].dataloader)):
|
||||||
|
self.before_iter(self.hooks_dict[self._mode])
|
||||||
|
if self.sample_args:
|
||||||
|
batch_data.update(self.sample_args.get_lowercase_dict())
|
||||||
|
with torch.autocast(device_type='cuda',
|
||||||
|
enabled=self.use_amp,
|
||||||
|
dtype=self.dtype):
|
||||||
|
results = self.run_step_eval(transfer_data_to_cuda(batch_data),
|
||||||
|
batch_idx,
|
||||||
|
step=self.total_iter,
|
||||||
|
rank=we.rank)
|
||||||
|
all_results.extend(results)
|
||||||
|
self.after_iter(self.hooks_dict[self._mode])
|
||||||
|
log_data, log_label = self.save_results(all_results)
|
||||||
|
self.register_probe({'test_label': log_label})
|
||||||
|
self.register_probe({
|
||||||
|
'test_image':
|
||||||
|
ProbeData(log_data,
|
||||||
|
is_image=True,
|
||||||
|
build_html=True,
|
||||||
|
build_label=log_label)
|
||||||
|
})
|
||||||
|
|
||||||
|
self.after_all_iter(self.hooks_dict[self._mode])
|
||||||
|
|
||||||
|
def save_results(self, results):
|
||||||
|
log_data, log_label = [], []
|
||||||
|
for result in results:
|
||||||
|
ret_images, ret_labels = [], []
|
||||||
|
edit_image = result.get('edit_image', None)
|
||||||
|
edit_mask = result.get('edit_mask', None)
|
||||||
|
if edit_image is not None:
|
||||||
|
for i, edit_img in enumerate(result['edit_image']):
|
||||||
|
if edit_img is None:
|
||||||
|
continue
|
||||||
|
ret_images.append((edit_img.permute(1, 2, 0).cpu().numpy() * 255).astype(np.uint8))
|
||||||
|
ret_labels.append(f'edit_image{i}; ')
|
||||||
|
if edit_mask is not None:
|
||||||
|
ret_images.append((edit_mask[i].permute(1, 2, 0).cpu().numpy() * 255).astype(np.uint8))
|
||||||
|
ret_labels.append(f'edit_mask{i}; ')
|
||||||
|
|
||||||
|
target_image = result.get('target_image', None)
|
||||||
|
target_mask = result.get('target_mask', None)
|
||||||
|
if target_image is not None:
|
||||||
|
ret_images.append((target_image.permute(1, 2, 0).cpu().numpy() * 255).astype(np.uint8))
|
||||||
|
ret_labels.append(f'target_image; ')
|
||||||
|
if target_mask is not None:
|
||||||
|
ret_images.append((target_mask.permute(1, 2, 0).cpu().numpy() * 255).astype(np.uint8))
|
||||||
|
ret_labels.append(f'target_mask; ')
|
||||||
|
teacher_image = result.get('image', None)
|
||||||
|
if teacher_image is not None:
|
||||||
|
ret_images.append((teacher_image.permute(1, 2, 0).cpu().numpy() * 255).astype(np.uint8))
|
||||||
|
ret_labels.append(f"teacher_image")
|
||||||
|
reconstruct_image = result.get('reconstruct_image', None)
|
||||||
|
if reconstruct_image is not None:
|
||||||
|
ret_images.append((reconstruct_image.permute(1, 2, 0).cpu().numpy() * 255).astype(np.uint8))
|
||||||
|
ret_labels.append(f"{result['instruction']}")
|
||||||
|
log_data.append(ret_images)
|
||||||
|
log_label.append(ret_labels)
|
||||||
|
return log_data, log_label
|
||||||
|
@property
|
||||||
|
def probe_data(self):
|
||||||
|
if not we.debug and self.mode == 'train':
|
||||||
|
batch_data = transfer_data_to_cuda(self.current_batch_data[self.mode])
|
||||||
|
self.eval_mode()
|
||||||
|
with torch.autocast(device_type='cuda',
|
||||||
|
enabled=self.use_amp,
|
||||||
|
dtype=self.dtype):
|
||||||
|
batch_data['log_num'] = self.log_train_num
|
||||||
|
batch_data.update(self.sample_args.get_lowercase_dict())
|
||||||
|
results = self.run_step_eval(batch_data)
|
||||||
|
self.train_mode()
|
||||||
|
log_data, log_label = self.save_results(results)
|
||||||
|
self.register_probe({
|
||||||
|
'train_image':
|
||||||
|
ProbeData(log_data,
|
||||||
|
is_image=True,
|
||||||
|
build_html=True,
|
||||||
|
build_label=log_label)
|
||||||
|
})
|
||||||
|
self.register_probe({'train_label': log_label})
|
||||||
|
if self.probe_prompt:
|
||||||
|
self.eval_mode()
|
||||||
|
all_results = []
|
||||||
|
for prompt in self.probe_prompt:
|
||||||
|
with torch.autocast(device_type='cuda',
|
||||||
|
enabled=self.use_amp,
|
||||||
|
dtype=self.dtype):
|
||||||
|
batch_data = {
|
||||||
|
"prompt": [[prompt]],
|
||||||
|
"image": [torch.zeros(3, self.probe_hw[0], self.probe_hw[1])],
|
||||||
|
"image_mask": [torch.ones(1, self.probe_hw[0], self.probe_hw[1])],
|
||||||
|
"src_image_list": [[]],
|
||||||
|
"src_mask_list": [[]],
|
||||||
|
"edit_id": [[]],
|
||||||
|
"height": self.probe_hw[0],
|
||||||
|
"width": self.probe_hw[1]
|
||||||
|
}
|
||||||
|
batch_data.update(self.sample_args.get_lowercase_dict())
|
||||||
|
results = self.run_step_eval(batch_data)
|
||||||
|
all_results.extend(results)
|
||||||
|
self.train_mode()
|
||||||
|
log_data, log_label = self.save_results(all_results)
|
||||||
|
self.register_probe({
|
||||||
|
'probe_image':
|
||||||
|
ProbeData(log_data,
|
||||||
|
is_image=True,
|
||||||
|
build_html=True,
|
||||||
|
build_label=log_label)
|
||||||
|
})
|
||||||
|
|
||||||
|
return super(LatentDiffusionSolver, self).probe_data
|
||||||
@@ -217,6 +217,7 @@ class LatentDiffusionSolver(BaseSolver):
|
|||||||
self.tuner_cfg = cfg.get('TUNER', None)
|
self.tuner_cfg = cfg.get('TUNER', None)
|
||||||
self.freeze_cfg = cfg.get('FREEZE', None)
|
self.freeze_cfg = cfg.get('FREEZE', None)
|
||||||
self.log_train_num = cfg.get("LOG_TRAIN_NUM", -1)
|
self.log_train_num = cfg.get("LOG_TRAIN_NUM", -1)
|
||||||
|
self.timesteps = cfg.get("TIMESTEPS", 1000)
|
||||||
|
|
||||||
def set_up(self):
|
def set_up(self):
|
||||||
self.construct_data()
|
self.construct_data()
|
||||||
@@ -272,6 +273,12 @@ class LatentDiffusionSolver(BaseSolver):
|
|||||||
module_keys = [key for key, _ in self.model.named_modules()]
|
module_keys = [key for key, _ in self.model.named_modules()]
|
||||||
self.logger.info(module_keys)
|
self.logger.info(module_keys)
|
||||||
|
|
||||||
|
def train_parameters(self):
|
||||||
|
model = self.model
|
||||||
|
for key, val in model.named_parameters():
|
||||||
|
if val.requires_grad:
|
||||||
|
yield val
|
||||||
|
|
||||||
def model_to_device(self):
|
def model_to_device(self):
|
||||||
self.model = self.model.to(we.device_id)
|
self.model = self.model.to(we.device_id)
|
||||||
|
|
||||||
@@ -285,8 +292,15 @@ class LatentDiffusionSolver(BaseSolver):
|
|||||||
self.cfg.OPTIMIZER.LEARNING_RATE *= all_batch_size
|
self.cfg.OPTIMIZER.LEARNING_RATE *= all_batch_size
|
||||||
self.cfg.OPTIMIZER.LEARNING_RATE /= 640
|
self.cfg.OPTIMIZER.LEARNING_RATE /= 640
|
||||||
|
|
||||||
|
def get_params(self, module):
|
||||||
|
train_params = []
|
||||||
|
for param in module.parameters():
|
||||||
|
if param.requires_grad:
|
||||||
|
train_params.append(param)
|
||||||
|
return train_params
|
||||||
|
|
||||||
def init_opti(self):
|
def init_opti(self):
|
||||||
import torch.cuda.amp as amp
|
import torch.amp as amp
|
||||||
import torch.distributed as dist
|
import torch.distributed as dist
|
||||||
|
|
||||||
if we.is_distributed:
|
if we.is_distributed:
|
||||||
@@ -383,7 +397,7 @@ class LatentDiffusionSolver(BaseSolver):
|
|||||||
for module in self.train_modules:
|
for module in self.train_modules:
|
||||||
if hasattr(self.model, module):
|
if hasattr(self.model, module):
|
||||||
current_module = getattr(self.model, module)
|
current_module = getattr(self.model, module)
|
||||||
train_params += list(current_module.parameters())
|
train_params += self.get_params(current_module)
|
||||||
|
|
||||||
self.optimizer = OPTIMIZERS.build(self.cfg.OPTIMIZER,
|
self.optimizer = OPTIMIZERS.build(self.cfg.OPTIMIZER,
|
||||||
logger=self.logger,
|
logger=self.logger,
|
||||||
@@ -398,12 +412,12 @@ class LatentDiffusionSolver(BaseSolver):
|
|||||||
self.optimizer = OPTIMIZERS.build(
|
self.optimizer = OPTIMIZERS.build(
|
||||||
self.cfg.OPTIMIZER,
|
self.cfg.OPTIMIZER,
|
||||||
logger=self.logger,
|
logger=self.logger,
|
||||||
parameters=self.model.parameters())
|
parameters=self.get_params(self.model))
|
||||||
else:
|
else:
|
||||||
self.optimizer = OPTIMIZERS.build(
|
self.optimizer = OPTIMIZERS.build(
|
||||||
self.cfg.OPTIMIZER,
|
self.cfg.OPTIMIZER,
|
||||||
logger=self.logger,
|
logger=self.logger,
|
||||||
parameters=self.model.parameters())
|
parameters=self.get_params(self.model))
|
||||||
|
|
||||||
if self.cfg.have('LR_SCHEDULER') and self.optimizer is not None:
|
if self.cfg.have('LR_SCHEDULER') and self.optimizer is not None:
|
||||||
self.cfg.LR_SCHEDULER.TOTAL_STEPS = self.max_steps
|
self.cfg.LR_SCHEDULER.TOTAL_STEPS = self.max_steps
|
||||||
@@ -422,8 +436,8 @@ class LatentDiffusionSolver(BaseSolver):
|
|||||||
process_group=None)
|
process_group=None)
|
||||||
else:
|
else:
|
||||||
self.scaler = amp.GradScaler(enabled=self.enable_gradscaler)
|
self.scaler = amp.GradScaler(enabled=self.enable_gradscaler)
|
||||||
elif self.cfg.DTYPE in ['float16']:
|
elif self.cfg.DTYPE in ['float16', 'bfloat16']:
|
||||||
self.scaler = amp.GradScaler()
|
self.scaler = amp.GradScaler(enabled=self.enable_gradscaler)
|
||||||
else:
|
else:
|
||||||
self.scaler = None
|
self.scaler = None
|
||||||
else:
|
else:
|
||||||
@@ -736,16 +750,40 @@ class LatentDiffusionSolver(BaseSolver):
|
|||||||
|
|
||||||
if model is None:
|
if model is None:
|
||||||
model = self.model
|
model = self.model
|
||||||
swift_cfg_dict = {}
|
|
||||||
for t_id, t_cfg in enumerate(tuner_cfg):
|
if isinstance(tuner_cfg, str):
|
||||||
cfg_name = t_cfg['NAME']
|
|
||||||
init_config = TUNERS.build(t_cfg, logger=self.logger)()
|
|
||||||
if init_config is None:
|
|
||||||
continue
|
|
||||||
swift_cfg_dict[f'{t_id}_{cfg_name}'] = init_config
|
|
||||||
if len(swift_cfg_dict) > 0:
|
|
||||||
from swift import Swift
|
from swift import Swift
|
||||||
model = Swift.prepare_model(self.model, config=swift_cfg_dict, autocast_adapter_dtype=False)
|
from scepter.modules.utils.file_system import FS
|
||||||
|
with FS.get_dir_to_local_dir(tuner_cfg, wait_finish=True) as local_dir:
|
||||||
|
model = Swift.from_pretrained(model, local_dir, autocast_adapter_dtype=False)
|
||||||
|
self.logger.info(f'Load tuner model from {tuner_cfg}')
|
||||||
|
else:
|
||||||
|
swift_cfg_dict = {}
|
||||||
|
swfit_ckpts = {}
|
||||||
|
for t_id, t_cfg in enumerate(tuner_cfg):
|
||||||
|
if 'PRETRAINED_MODEL' in t_cfg:
|
||||||
|
pretrained_model = t_cfg.pop('PRETRAINED_MODEL')
|
||||||
|
from scepter.modules.utils.file_system import FS
|
||||||
|
with FS.get_from(pretrained_model, wait_finish=True) as local_path:
|
||||||
|
if local_path.endswith('safetensors'):
|
||||||
|
from safetensors.torch import load_file as load_safetensors
|
||||||
|
ckpt = load_safetensors(local_path)
|
||||||
|
else:
|
||||||
|
ckpt = torch.load(local_path, map_location='cpu', weights_only=True)
|
||||||
|
swfit_ckpts.update(ckpt)
|
||||||
|
cfg_name = t_cfg['NAME']
|
||||||
|
init_config = TUNERS.build(t_cfg, logger=self.logger)()
|
||||||
|
if init_config is None:
|
||||||
|
continue
|
||||||
|
swift_cfg_dict[f'{t_id}_{cfg_name}'] = init_config
|
||||||
|
|
||||||
|
if len(swift_cfg_dict) > 0:
|
||||||
|
from swift import Swift
|
||||||
|
model = Swift.prepare_model(self.model, config=swift_cfg_dict, autocast_adapter_dtype=False)
|
||||||
|
if len(swfit_ckpts) > 0:
|
||||||
|
swfit_ckpts = {k.replace('transformer.', 'model.').replace('lora_A.weight', 'lora_A.0_SwiftLoRA.weight').replace('lora_B.weight', 'lora_B.0_SwiftLoRA.weight'): v for k, v in swfit_ckpts.items()}
|
||||||
|
model.load_state_dict(swfit_ckpts, strict=True)
|
||||||
|
self.logger.info(f'Restored from TUNER with length of {len(swfit_ckpts)}')
|
||||||
self.logger.info([(key, param.shape) for key, param in model.named_parameters() if param.requires_grad])
|
self.logger.info([(key, param.shape) for key, param in model.named_parameters() if param.requires_grad])
|
||||||
return model
|
return model
|
||||||
|
|
||||||
|
|||||||
@@ -24,23 +24,31 @@ class LatentDiffusionVideoSolver(LatentDiffusionSolver):
|
|||||||
for result in results:
|
for result in results:
|
||||||
ret_videos, ret_labels = [], []
|
ret_videos, ret_labels = [], []
|
||||||
if 'edit_video' in result:
|
if 'edit_video' in result:
|
||||||
ret_videos.append((result['edit_video'].permute(1, 2, 3, 0).cpu().numpy() *
|
ret_videos.append((result['edit_video'].permute(1, 2, 3, 0)*255).cpu().numpy().astype(np.uint8))
|
||||||
255).astype(np.uint8))
|
|
||||||
ret_labels.append("left: edit video")
|
ret_labels.append("left: edit video")
|
||||||
if 'edit_image' in result:
|
if 'edit_image' in result:
|
||||||
ret_videos.append((result['edit_image'].permute(1, 2, 3, 0).cpu().numpy() *
|
ret_videos.append((result['edit_image'].permute(1, 2, 3, 0)*255).cpu().numpy().astype(np.uint8))
|
||||||
255).astype(np.uint8))
|
|
||||||
ret_labels.append("left: edit image")
|
ret_labels.append("left: edit image")
|
||||||
|
if 'edit_mask' in result:
|
||||||
|
if len(result['edit_mask'].shape) == 4:
|
||||||
|
ret_videos.append((result['edit_mask'].permute(1, 2, 3, 0)*255).cpu().numpy().astype(np.uint8))
|
||||||
|
elif len(result['edit_mask'].shape) == 3:
|
||||||
|
if result['edit_mask'].shape[0] == 1:
|
||||||
|
result['edit_mask'] = result['edit_mask'].repeat(3, 1, 1)
|
||||||
|
ret_videos.append(((result['edit_mask'].permute(1, 2, 0)*255).cpu().numpy()[None, ...]).astype(np.uint8))
|
||||||
|
else:
|
||||||
|
if result['edit_mask'].shape[0] == 1:
|
||||||
|
result['edit_mask'] = result['edit_mask'].repeat(3, 1, 1, 1)
|
||||||
|
ret_videos.append(((result['edit_mask'].permute(1, 2, 3, 0)*255).cpu().numpy()).astype(np.uint8))
|
||||||
|
ret_labels.append("middle: edit mask")
|
||||||
if 'target_video' in result:
|
if 'target_video' in result:
|
||||||
if len(ret_videos) > 0:
|
if len(ret_videos) > 0:
|
||||||
ret_labels.append("middle: target video")
|
ret_labels.append("middle: target video")
|
||||||
else:
|
else:
|
||||||
ret_labels.append("left: target video")
|
ret_labels.append("left: target video")
|
||||||
ret_videos.append((result['target_video'].permute(1, 2, 3, 0).cpu().numpy() *
|
ret_videos.append((result['target_video'].permute(1, 2, 3, 0)*255).cpu().numpy().astype(np.uint8))
|
||||||
255).astype(np.uint8))
|
|
||||||
|
|
||||||
ret_videos.append((result['reconstruct_video'].permute(1, 2, 3, 0).cpu().numpy() *
|
ret_videos.append((result['reconstruct_video'].permute(1, 2, 3, 0)*255).cpu().numpy().astype(np.uint8))
|
||||||
255).astype(np.uint8))
|
|
||||||
ret_labels.append("right: generation video" + " Prompt: " + result['instruction'])
|
ret_labels.append("right: generation video" + " Prompt: " + result['instruction'])
|
||||||
|
|
||||||
log_data.append(ret_videos)
|
log_data.append(ret_videos)
|
||||||
@@ -70,15 +78,11 @@ class LatentDiffusionVideoSolver(LatentDiffusionSolver):
|
|||||||
'batch_size': len(batch_data['prompt'])
|
'batch_size': len(batch_data['prompt'])
|
||||||
})
|
})
|
||||||
self.current_batch_data[self.mode] = batch_data
|
self.current_batch_data[self.mode] = batch_data
|
||||||
if self.sample_args:
|
|
||||||
self.current_batch_data[self.mode].update(
|
|
||||||
self.sample_args.get_lowercase_dict())
|
|
||||||
batch_data = transfer_data_to_cuda(batch_data)
|
|
||||||
with torch.autocast(device_type='cuda',
|
with torch.autocast(device_type='cuda',
|
||||||
enabled=self.use_amp,
|
enabled=self.use_amp,
|
||||||
dtype=self.dtype):
|
dtype=self.dtype):
|
||||||
results = self.run_step_train(
|
results = self.run_step_train(
|
||||||
batch_data,
|
transfer_data_to_cuda(batch_data),
|
||||||
step,
|
step,
|
||||||
step=self.total_iter,
|
step=self.total_iter,
|
||||||
rank=we.rank)
|
rank=we.rank)
|
||||||
@@ -124,6 +128,21 @@ class LatentDiffusionVideoSolver(LatentDiffusionSolver):
|
|||||||
})
|
})
|
||||||
self.after_all_iter(self.hooks_dict[self._mode])
|
self.after_all_iter(self.hooks_dict[self._mode])
|
||||||
|
|
||||||
|
def run_step_val(self, batch_data, noise_generator=None):
|
||||||
|
loss_dict = {}
|
||||||
|
batch_data = transfer_data_to_cuda(batch_data)
|
||||||
|
with torch.autocast(device_type='cuda',
|
||||||
|
enabled=self.use_amp,
|
||||||
|
dtype=self.dtype):
|
||||||
|
if hasattr(self.model, 'module'):
|
||||||
|
results = self.model.module.forward_train(**batch_data)
|
||||||
|
else:
|
||||||
|
results = self.model.forward_train(**batch_data)
|
||||||
|
loss = results['loss']
|
||||||
|
for sample_id in batch_data['sample_id']:
|
||||||
|
loss_dict[sample_id] = loss.detach().cpu().numpy()
|
||||||
|
return loss_dict
|
||||||
|
|
||||||
@torch.no_grad()
|
@torch.no_grad()
|
||||||
def run_test(self):
|
def run_test(self):
|
||||||
self.test_mode()
|
self.test_mode()
|
||||||
@@ -166,7 +185,7 @@ class LatentDiffusionVideoSolver(LatentDiffusionSolver):
|
|||||||
with torch.autocast(device_type='cuda',
|
with torch.autocast(device_type='cuda',
|
||||||
enabled=self.use_amp,
|
enabled=self.use_amp,
|
||||||
dtype=self.dtype):
|
dtype=self.dtype):
|
||||||
batch_data['log_train_num'] = self.log_train_num
|
batch_data['log_num'] = self.log_train_num
|
||||||
all_results = self.run_step_eval(transfer_data_to_cuda(batch_data))
|
all_results = self.run_step_eval(transfer_data_to_cuda(batch_data))
|
||||||
self.train_mode()
|
self.train_mode()
|
||||||
log_data, log_label = self.save_results(all_results)
|
log_data, log_label = self.save_results(all_results)
|
||||||
|
|||||||
@@ -1,16 +1,7 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
from typing import TYPE_CHECKING
|
||||||
from scepter.modules.solver.hooks.backward import BackwardHook
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
from scepter.modules.solver.hooks.checkpoint import CheckpointHook
|
|
||||||
from scepter.modules.solver.hooks.data_probe import ProbeDataHook
|
|
||||||
from scepter.modules.solver.hooks.ema import ModelEmaHook
|
|
||||||
from scepter.modules.solver.hooks.hook import Hook
|
|
||||||
from scepter.modules.solver.hooks.log import LogHook, TensorboardLogHook
|
|
||||||
from scepter.modules.solver.hooks.lr import LrHook
|
|
||||||
from scepter.modules.solver.hooks.registry import HOOKS
|
|
||||||
from scepter.modules.solver.hooks.safetensors import SafetensorsHook
|
|
||||||
from scepter.modules.solver.hooks.sampler import DistSamplerHook
|
|
||||||
"""
|
"""
|
||||||
Normally, hooks have priorities, below we recommend priority that runs fine (low score MEANS high priority)
|
Normally, hooks have priorities, below we recommend priority that runs fine (low score MEANS high priority)
|
||||||
BackwardHook: 0
|
BackwardHook: 0
|
||||||
@@ -46,8 +37,39 @@ after solve:
|
|||||||
TensorboardLogHook: close file handler
|
TensorboardLogHook: close file handler
|
||||||
"""
|
"""
|
||||||
|
|
||||||
__all__ = [
|
|
||||||
'HOOKS', 'BackwardHook', 'CheckpointHook', 'Hook', 'LrHook', 'LogHook',
|
if TYPE_CHECKING:
|
||||||
'TensorboardLogHook', 'DistSamplerHook', 'ProbeDataHook',
|
from scepter.modules.solver.hooks.backward import BackwardHook
|
||||||
'SafetensorsHook', 'ModelEmaHook'
|
from scepter.modules.solver.hooks.checkpoint import CheckpointHook
|
||||||
]
|
from scepter.modules.solver.hooks.data_probe import ProbeDataHook
|
||||||
|
from scepter.modules.solver.hooks.ema import ModelEmaHook
|
||||||
|
from scepter.modules.solver.hooks.hook import Hook
|
||||||
|
from scepter.modules.solver.hooks.log import LogHook, TensorboardLogHook
|
||||||
|
from scepter.modules.solver.hooks.lr import LrHook
|
||||||
|
from scepter.modules.solver.hooks.registry import HOOKS
|
||||||
|
from scepter.modules.solver.hooks.safetensors import SafetensorsHook
|
||||||
|
from scepter.modules.solver.hooks.sampler import DistSamplerHook
|
||||||
|
from scepter.modules.solver.hooks.val_loss import ValLossHook
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'backward': ['BackwardHook'],
|
||||||
|
'checkpoint': ['CheckpointHook'],
|
||||||
|
'data_probe': ['ProbeDataHook'],
|
||||||
|
'ema': ['ModelEmaHook'],
|
||||||
|
'hook': ['Hook'],
|
||||||
|
'log': ['LogHook', 'TensorboardLogHook'],
|
||||||
|
'lr': ['LrHook'],
|
||||||
|
'registry': ['HOOKS'],
|
||||||
|
'safetensors': ['SafetensorsHook'],
|
||||||
|
'sampler': ['DistSamplerHook'],
|
||||||
|
'val_loss': ['ValLossHook']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -112,10 +112,15 @@ class BackwardHook(Hook):
|
|||||||
f'Profiler stop after {self.profile_step} steps')
|
f'Profiler stop after {self.profile_step} steps')
|
||||||
FS.put_dir_from_local_dir(self._local_log_dir, self.log_dir)
|
FS.put_dir_from_local_dir(self._local_log_dir, self.log_dir)
|
||||||
|
|
||||||
def grad_clip(self, parameters):
|
def grad_clip(self, optimizer):
|
||||||
torch.nn.utils.clip_grad_norm_(parameters=parameters,
|
for params_group in optimizer.param_groups:
|
||||||
max_norm=self.gradient_clip,
|
train_params = []
|
||||||
norm_type=2)
|
for param in params_group['params']:
|
||||||
|
if param.requires_grad:
|
||||||
|
train_params.append(param)
|
||||||
|
# print(len(train_params), self.gradient_clip)
|
||||||
|
torch.nn.utils.clip_grad_norm_(parameters=train_params,
|
||||||
|
max_norm=self.gradient_clip)
|
||||||
|
|
||||||
def after_iter(self, solver):
|
def after_iter(self, solver):
|
||||||
if solver.optimizer is not None and solver.is_train_mode:
|
if solver.optimizer is not None and solver.is_train_mode:
|
||||||
@@ -131,9 +136,9 @@ class BackwardHook(Hook):
|
|||||||
# Suppose profiler run after backward, so we need to set backward_prev_step
|
# Suppose profiler run after backward, so we need to set backward_prev_step
|
||||||
# as the previous one step before the backward step
|
# as the previous one step before the backward step
|
||||||
if self.current_step % self.accumulate_step == 0:
|
if self.current_step % self.accumulate_step == 0:
|
||||||
|
solver.scaler.unscale_(solver.optimizer)
|
||||||
if self.gradient_clip > 0:
|
if self.gradient_clip > 0:
|
||||||
solver.scaler.unscale_(solver.optimizer)
|
self.grad_clip(solver.optimizer)
|
||||||
self.grad_clip(solver.train_parameters())
|
|
||||||
self.profile(solver)
|
self.profile(solver)
|
||||||
solver.scaler.step(solver.optimizer)
|
solver.scaler.step(solver.optimizer)
|
||||||
solver.scaler.update()
|
solver.scaler.update()
|
||||||
@@ -145,7 +150,7 @@ class BackwardHook(Hook):
|
|||||||
# as the previous one step before the backward step
|
# as the previous one step before the backward step
|
||||||
if self.current_step % self.accumulate_step == 0:
|
if self.current_step % self.accumulate_step == 0:
|
||||||
if self.gradient_clip > 0:
|
if self.gradient_clip > 0:
|
||||||
self.grad_clip(solver.train_parameters())
|
self.grad_clip(solver.optimizer)
|
||||||
self.profile(solver)
|
self.profile(solver)
|
||||||
solver.optimizer.step()
|
solver.optimizer.step()
|
||||||
solver.optimizer.zero_grad()
|
solver.optimizer.zero_grad()
|
||||||
|
|||||||
@@ -96,7 +96,7 @@ class CheckpointHook(Hook):
|
|||||||
with FS.get_from(solver.resume_from, wait_finish=True) as local_file:
|
with FS.get_from(solver.resume_from, wait_finish=True) as local_file:
|
||||||
solver.logger.info(f'Loading checkpoint from {solver.resume_from}')
|
solver.logger.info(f'Loading checkpoint from {solver.resume_from}')
|
||||||
checkpoint = torch.load(local_file,
|
checkpoint = torch.load(local_file,
|
||||||
map_location=torch.device('cpu'))
|
map_location=torch.device('cpu'), weights_only=True)
|
||||||
|
|
||||||
solver.load_checkpoint(checkpoint)
|
solver.load_checkpoint(checkpoint)
|
||||||
if self.save_best and '_CheckpointHook_best' in checkpoint:
|
if self.save_best and '_CheckpointHook_best' in checkpoint:
|
||||||
|
|||||||
@@ -0,0 +1,230 @@
|
|||||||
|
# -*- coding: utf-8 -*-
|
||||||
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
import json
|
||||||
|
import os
|
||||||
|
|
||||||
|
import numpy as np
|
||||||
|
import torch
|
||||||
|
from tqdm import tqdm
|
||||||
|
|
||||||
|
from scepter.modules.data.dataset import DATASETS
|
||||||
|
from scepter.modules.solver.hooks.hook import Hook
|
||||||
|
from scepter.modules.solver.hooks.registry import HOOKS
|
||||||
|
from scepter.modules.utils.config import dict_to_yaml
|
||||||
|
from scepter.modules.utils.distribute import barrier, gather_data, we
|
||||||
|
from scepter.modules.utils.file_system import FS
|
||||||
|
from scepter.modules.utils.math_plot import plot_multi_curves
|
||||||
|
|
||||||
|
_DEFAULT_VAL_PRIORITY = 200
|
||||||
|
|
||||||
|
|
||||||
|
def float_format(o):
|
||||||
|
if isinstance(o, float):
|
||||||
|
return f"{o: .6f}"
|
||||||
|
raise TypeError(f"Type {type(o)} not serializable")
|
||||||
|
|
||||||
|
|
||||||
|
@HOOKS.register_class()
|
||||||
|
class ValLossHook(Hook):
|
||||||
|
para_dict = [{
|
||||||
|
'PRIORITY': {
|
||||||
|
'value': _DEFAULT_VAL_PRIORITY,
|
||||||
|
'description': 'The priority for processing!'
|
||||||
|
},
|
||||||
|
'VAL_INTERVAL': {
|
||||||
|
'value': 1000,
|
||||||
|
'description': 'the interval for log print!'
|
||||||
|
},
|
||||||
|
'VAL_LIMITATION_SIZE': {
|
||||||
|
'value': 1000000,
|
||||||
|
'description': 'the limitation size for validation!'
|
||||||
|
},
|
||||||
|
'VAL_SEED': {
|
||||||
|
'value': 2025,
|
||||||
|
'description': 'the validation seed for t or generator sample!'
|
||||||
|
}
|
||||||
|
}]
|
||||||
|
|
||||||
|
def __init__(self, cfg, logger=None):
|
||||||
|
super(ValLossHook, self).__init__(cfg, logger=logger)
|
||||||
|
self.priority = cfg.get('PRIORITY', _DEFAULT_VAL_PRIORITY)
|
||||||
|
self.val_interval = cfg.get('VAL_INTERVAL', 1000)
|
||||||
|
self.val_dim = cfg.get('VAL_DIM', 'all')
|
||||||
|
self.meta_field = cfg.get('META_FIELD', ['edit_type', 'data_type'])
|
||||||
|
self.save_folder = cfg.get('SAVE_FOLDER', 'val_loss')
|
||||||
|
self.val_limitation_size = cfg.get('VAL_LIMITATION_SIZE', 1000000)
|
||||||
|
self.val_seed = cfg.get('VAL_SEED', 2025)
|
||||||
|
self.data = DATASETS.build(cfg.DATA, logger=logger)
|
||||||
|
|
||||||
|
def before_all_iter(self, solver):
|
||||||
|
solver.eval_mode()
|
||||||
|
self.eval_set_size = len(self.data.dataset)
|
||||||
|
if self.eval_set_size > self.val_limitation_size:
|
||||||
|
self.logger.info(
|
||||||
|
f"The samples number {self.eval_set_size} of validation set "
|
||||||
|
f"should not great than {self.val_limitation_size}")
|
||||||
|
assert self.eval_set_size < self.val_limitation_size
|
||||||
|
if not hasattr(solver, 'run_step_val'):
|
||||||
|
self.logger.info(
|
||||||
|
f"The val-loss hook should have the function run_step_val" # noqa
|
||||||
|
) # noqa
|
||||||
|
assert hasattr(solver, 'run_step_val')
|
||||||
|
if not self.data.batch_size == 1:
|
||||||
|
self.logger.info(
|
||||||
|
f"The batch_size of validation set should be 1 " # noqa
|
||||||
|
f"when you use the validation hook to make the results deterministic." # noqa
|
||||||
|
)
|
||||||
|
assert self.data.batch_size == 1
|
||||||
|
timestamp_generator = torch.Generator(device=we.device_id)
|
||||||
|
timestamp_generator.manual_seed(self.val_seed)
|
||||||
|
u = torch.rand((self.eval_set_size, ),
|
||||||
|
device=we.device_id,
|
||||||
|
generator=timestamp_generator)
|
||||||
|
self.t = (u * (solver.timesteps - 1)).round().long()
|
||||||
|
solver.val_interval = self.val_interval
|
||||||
|
solver.train_mode()
|
||||||
|
|
||||||
|
def get_val_loss(self, solver, step):
|
||||||
|
all_loss = []
|
||||||
|
# batch-size must be 1
|
||||||
|
for batch_data in tqdm(self.data.dataloader):
|
||||||
|
# generate t list
|
||||||
|
sample_id = int(batch_data['sample_id'][0])
|
||||||
|
meta_info = {m_f: batch_data[m_f][0] for m_f in self.meta_field}
|
||||||
|
meta_info['sample_id'] = sample_id
|
||||||
|
|
||||||
|
batch_data['t'] = torch.stack(
|
||||||
|
[self.t[sample_id % self.eval_set_size]])
|
||||||
|
noise_generator = torch.Generator(device=we.device_id)
|
||||||
|
noise_generator.manual_seed(sample_id + 10000 * self.val_seed)
|
||||||
|
# get generator according to the sample_id
|
||||||
|
with torch.no_grad():
|
||||||
|
loss = solver.run_step_val(batch_data, noise_generator)
|
||||||
|
meta_info['loss'] = float(loss[sample_id])
|
||||||
|
all_loss.append(meta_info)
|
||||||
|
all_loss = json.dumps(all_loss, default=float_format)
|
||||||
|
all_loss = gather_data([all_loss])
|
||||||
|
if we.rank == 0:
|
||||||
|
reduce_loss = []
|
||||||
|
for loss in all_loss:
|
||||||
|
reduce_loss.extend(json.loads(loss))
|
||||||
|
compute_results = self.compute_avg_loss(reduce_loss)
|
||||||
|
self.save_record(solver, compute_results, reduce_loss, step)
|
||||||
|
return
|
||||||
|
|
||||||
|
def compute_avg_loss(self, loss_list):
|
||||||
|
all_avg_ls = []
|
||||||
|
avg_ls = {}
|
||||||
|
for ls in loss_list:
|
||||||
|
for m_f in self.meta_field:
|
||||||
|
m_f_v = ls[m_f]
|
||||||
|
ls_key = m_f + '_' + m_f_v
|
||||||
|
if ls_key not in avg_ls:
|
||||||
|
avg_ls[ls_key] = []
|
||||||
|
avg_ls[ls_key].append(ls['loss'])
|
||||||
|
all_avg_ls.append(ls['loss'])
|
||||||
|
compute_results = {
|
||||||
|
'all': sum(all_avg_ls) / len(all_avg_ls),
|
||||||
|
}
|
||||||
|
compute_results.update(
|
||||||
|
{m_f: sum(avg_ls[m_f]) / len(avg_ls[m_f])
|
||||||
|
for m_f in avg_ls})
|
||||||
|
return compute_results
|
||||||
|
|
||||||
|
def save_record(self, solver, compute_results, all_loss, step):
|
||||||
|
save_folder = os.path.join(solver.work_dir, self.save_folder)
|
||||||
|
# save history
|
||||||
|
save_history = os.path.join(save_folder, 'history.json')
|
||||||
|
|
||||||
|
draw_curve = False
|
||||||
|
|
||||||
|
if FS.exists(save_history):
|
||||||
|
results = json.loads(FS.get_object(save_history).decode())
|
||||||
|
all_loss = {loss['sample_id']: loss for loss in all_loss}
|
||||||
|
for loss in results['detail']:
|
||||||
|
loss['loss'] = {int(k): v for k, v in loss['loss'].items()}
|
||||||
|
loss['loss'][step] = all_loss[loss['sample_id']]['loss']
|
||||||
|
for k, v in compute_results.items():
|
||||||
|
results['summary'][k] = {
|
||||||
|
int(kk): vv
|
||||||
|
for kk, vv in results['summary'][k].items()
|
||||||
|
}
|
||||||
|
results['summary'][k][step] = v
|
||||||
|
draw_curve = True
|
||||||
|
else:
|
||||||
|
results = {'detail': [], 'summary': {}}
|
||||||
|
for loss in all_loss:
|
||||||
|
loss_v = loss.pop('loss')
|
||||||
|
loss['loss'] = {step: loss_v}
|
||||||
|
results['detail'].append(loss)
|
||||||
|
for k, v in compute_results.items():
|
||||||
|
if k not in results['summary']:
|
||||||
|
results['summary'][k] = {}
|
||||||
|
results['summary'][k][step] = v
|
||||||
|
#
|
||||||
|
FS.put_object(
|
||||||
|
json.dumps(results, default=float_format).encode(), save_history)
|
||||||
|
# plot current curve
|
||||||
|
if draw_curve:
|
||||||
|
self.plot_results(results['summary'],
|
||||||
|
os.path.join(save_folder, 'curve'))
|
||||||
|
# print current log
|
||||||
|
print_msg = ''
|
||||||
|
for k, v in compute_results.items():
|
||||||
|
print_msg += f"{k}: {v: .4f} "
|
||||||
|
self.logger.info(f"Step {step} validation loss: {print_msg}")
|
||||||
|
|
||||||
|
def plot_results(self, plot_data, save_folder):
|
||||||
|
y = []
|
||||||
|
steps = []
|
||||||
|
# one image
|
||||||
|
for label, curve_data in plot_data.items():
|
||||||
|
curve_data = [[step, value] for step, value in curve_data.items()]
|
||||||
|
curve_data.sort(key=lambda x: x[0])
|
||||||
|
steps = [step for step, value in curve_data]
|
||||||
|
value = [value for step, value in curve_data]
|
||||||
|
k_y = [{'data': np.array(value), 'label': label}]
|
||||||
|
save_path = os.path.join(save_folder, 'detail', f"{label}.png")
|
||||||
|
with FS.put_to(save_path) as local_file:
|
||||||
|
plot_multi_curves(x=np.array(steps),
|
||||||
|
y=k_y,
|
||||||
|
x_label='steps',
|
||||||
|
y_label=None,
|
||||||
|
title=f"{label}'s validation loss",
|
||||||
|
save_path=local_file)
|
||||||
|
y = y + k_y
|
||||||
|
if len(steps) > 0:
|
||||||
|
save_path = os.path.join(save_folder, f"summary.png") # noqa
|
||||||
|
with FS.put_to(save_path) as local_file:
|
||||||
|
plot_multi_curves(
|
||||||
|
x=np.array(steps),
|
||||||
|
y=y,
|
||||||
|
x_label='steps',
|
||||||
|
y_label=None,
|
||||||
|
title=f"validation loss", # noqa
|
||||||
|
save_path=local_file)
|
||||||
|
|
||||||
|
def after_iter(self, solver):
|
||||||
|
if solver.mode == 'train' and solver.total_iter % self.val_interval == 0:
|
||||||
|
step = solver.total_iter
|
||||||
|
solver.eval_mode()
|
||||||
|
self.get_val_loss(solver, step)
|
||||||
|
solver.train_mode()
|
||||||
|
torch.cuda.synchronize()
|
||||||
|
barrier()
|
||||||
|
|
||||||
|
def after_all_iter(self, solver):
|
||||||
|
if solver.mode == 'train':
|
||||||
|
step = solver.total_iter
|
||||||
|
solver.eval_mode()
|
||||||
|
self.get_val_loss(solver, step)
|
||||||
|
solver.train_mode()
|
||||||
|
torch.cuda.synchronize()
|
||||||
|
barrier()
|
||||||
|
|
||||||
|
@staticmethod
|
||||||
|
def get_config_template():
|
||||||
|
return dict_to_yaml('HOOK',
|
||||||
|
__class__.__name__,
|
||||||
|
ValLossHook.para_dict,
|
||||||
|
set_name=True)
|
||||||
@@ -17,8 +17,11 @@ def build_solver(cfg, registry, logger=None, *args, **kwargs):
|
|||||||
f'registry must be type Registry, got {type(registry)}')
|
f'registry must be type Registry, got {type(registry)}')
|
||||||
|
|
||||||
cfg = deep_copy(cfg)
|
cfg = deep_copy(cfg)
|
||||||
|
|
||||||
req_type = cfg.get('NAME')
|
req_type = cfg.get('NAME')
|
||||||
|
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
sig = (registry.name.upper(), req_type)
|
||||||
|
LazyImportModule.import_module(sig)
|
||||||
if isinstance(req_type, str):
|
if isinstance(req_type, str):
|
||||||
req_type_entry = registry.get(req_type)
|
req_type_entry = registry.get(req_type)
|
||||||
if req_type_entry is None:
|
if req_type_entry is None:
|
||||||
|
|||||||
@@ -1,27 +1,59 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
|
from typing import TYPE_CHECKING
|
||||||
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
from scepter.modules.transform.augmention import ColorJitterGeneral
|
|
||||||
from scepter.modules.transform.compose import Compose
|
if TYPE_CHECKING:
|
||||||
from scepter.modules.transform.identity import Identity
|
from scepter.modules.transform.augmention import ColorJitterGeneral
|
||||||
from scepter.modules.transform.image import (CenterCrop, FlexibleCenterCrop,
|
from scepter.modules.transform.compose import Compose
|
||||||
FlexibleResize, ImageToTensor,
|
from scepter.modules.transform.identity import Identity
|
||||||
ImageTransform, Normalize,
|
from scepter.modules.transform.image import (CenterCrop, FlexibleCenterCrop,
|
||||||
RandomHorizontalFlip,
|
FlexibleResize, ImageToTensor,
|
||||||
RandomResizedCrop, Resize)
|
ImageTransform, Normalize,
|
||||||
from scepter.modules.transform.io import (LoadCvImageFromFile,
|
RandomHorizontalFlip,
|
||||||
LoadImageFromFile,
|
RandomResizedCrop, Resize)
|
||||||
LoadImageFromFileList,
|
from scepter.modules.transform.io import (LoadCvImageFromFile,
|
||||||
LoadPILImageFromFile)
|
LoadImageFromFile,
|
||||||
from scepter.modules.transform.io_video import (DecodeVideoToTensor,
|
LoadImageFromFileList,
|
||||||
LoadVideoFromFile)
|
LoadPILImageFromFile)
|
||||||
from scepter.modules.transform.registry import TRANSFORMS, build_pipeline
|
from scepter.modules.transform.io_video import (DecodeVideoToTensor,
|
||||||
from scepter.modules.transform.tensor import (Rename, RenameMeta, Select,
|
LoadVideoFromFile)
|
||||||
TemplateStr, ToNumpy, ToTensor)
|
from scepter.modules.transform.registry import TRANSFORMS, build_pipeline
|
||||||
from scepter.modules.transform.transform_xl import FlexibleCropXL
|
from scepter.modules.transform.tensor import (Rename, RenameMeta, Select,
|
||||||
from scepter.modules.transform.video import (AutoResizedCropVideo,
|
TemplateStr, ToNumpy, ToTensor)
|
||||||
CenterCropVideo, NormalizeVideo,
|
from scepter.modules.transform.transform_xl import FlexibleCropXL
|
||||||
RandomHorizontalFlipVideo,
|
from scepter.modules.transform.video import (AutoResizedCropVideo,
|
||||||
RandomResizedCropVideo,
|
CenterCropVideo, NormalizeVideo,
|
||||||
ResizeVideo, VideoToTensor,
|
RandomHorizontalFlipVideo,
|
||||||
VideoTransform)
|
RandomResizedCropVideo,
|
||||||
|
ResizeVideo, VideoToTensor,
|
||||||
|
VideoTransform)
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'augmention': ['ColorJitterGeneral'],
|
||||||
|
'compose': ['Compose'],
|
||||||
|
'identity': ['Identity'],
|
||||||
|
'image': ['CenterCrop', 'FlexibleCenterCrop', 'FlexibleResize',
|
||||||
|
'ImageToTensor', 'ImageTransform', 'Normalize',
|
||||||
|
'RandomHorizontalFlip', 'RandomResizedCrop', 'Resize'],
|
||||||
|
'io': ['LoadCvImageFromFile', 'LoadImageFromFile',
|
||||||
|
'LoadImageFromFileList', 'LoadPILImageFromFile'],
|
||||||
|
'io_video': ['DecodeVideoToTensor', 'LoadVideoFromFile'],
|
||||||
|
'registry': ['TRANSFORMS', 'build_pipeline'],
|
||||||
|
'tensor': ['Rename', 'RenameMeta', 'Select', 'TemplateStr',
|
||||||
|
'ToNumpy', 'ToTensor'],
|
||||||
|
'transform_xl': ['FlexibleCropXL'],
|
||||||
|
'video': ['AutoResizedCropVideo', 'CenterCropVideo', 'NormalizeVideo',
|
||||||
|
'RandomHorizontalFlipVideo', 'RandomResizedCropVideo',
|
||||||
|
'ResizeVideo', 'VideoToTensor', 'VideoTransform']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
@@ -1,4 +1,23 @@
|
|||||||
# -*- coding: utf-8 -*-
|
# -*- coding: utf-8 -*-
|
||||||
# Copyright (c) Alibaba, Inc. and its affiliates.
|
# Copyright (c) Alibaba, Inc. and its affiliates.
|
||||||
from scepter.modules.utils import (config, distribute, file_clients,
|
from typing import TYPE_CHECKING
|
||||||
file_system, module_transform)
|
from scepter.modules.utils.import_utils import LazyImportModule
|
||||||
|
|
||||||
|
|
||||||
|
if TYPE_CHECKING:
|
||||||
|
from scepter.modules.utils import (config, distribute, file_clients,
|
||||||
|
file_system, module_transform)
|
||||||
|
else:
|
||||||
|
_import_structure = {
|
||||||
|
'utils': ['config', 'distribute', 'file_clients',
|
||||||
|
'file_system', 'module_transform']
|
||||||
|
}
|
||||||
|
|
||||||
|
import sys
|
||||||
|
sys.modules[__name__] = LazyImportModule(
|
||||||
|
__name__,
|
||||||
|
globals()['__file__'],
|
||||||
|
_import_structure,
|
||||||
|
module_spec=__spec__,
|
||||||
|
extra_objects={},
|
||||||
|
)
|
||||||
|
|||||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user