
131 lines
7.1 KiB
Markdown
131 lines
7.1 KiB
Markdown
|
|
# StyleBooth: Image Style Editing with Multimodal Instruction
|
|
|
|
Zhen Han, Chaojie Mao, Zeyinzi Jiang, Yulin Pan, Jingfeng Zhang
|
|
|
|
Alibaba Group
|
|
|
|
[[paper](https://arxiv.org/abs/2404.12154)][[Model](https://modelscope.cn/models/iic/stylebooth/summary)] [[Dataset](https://modelscope.cn/models/iic/stylebooth/summary)]
|
|
|
|
## Abstract
|
|
|
|
Given an original image, image editing aims to generate an image that align with the provided instruction. The challenges are to accept multimodal inputs as instructions and a scarcity of high-quality training data, including crucial triplets of source/target image pairs and multimodal (text and image) instructions. In this paper, we focus on image style editing and present <strong>StyleBooth</strong>, a method that proposes a comprehensive framework for image editing and a feasible strategy for building a high-quality style editing dataset. We integrate encoded textual instruction and image exemplar as a unified condition for diffusion model, enabling the editing of original image following <strong>multimodal instructions</strong>. Furthermore, by <strong>iterative style-destyle tuning and editing</strong> and usability filtering, the StyleBooth dataset provides content-consistent stylized/plain image pairs in various categories of styles. To show the flexibility of StyleBooth, we conduct experiments on diverse tasks, such as textbased style editing, exemplar-based style editing and compositional style editing. The results demonstrate that the quality and variety of training data significantly enhance the ability to preserve content and improve the overall quality of generated images in editing tasks.
|
|
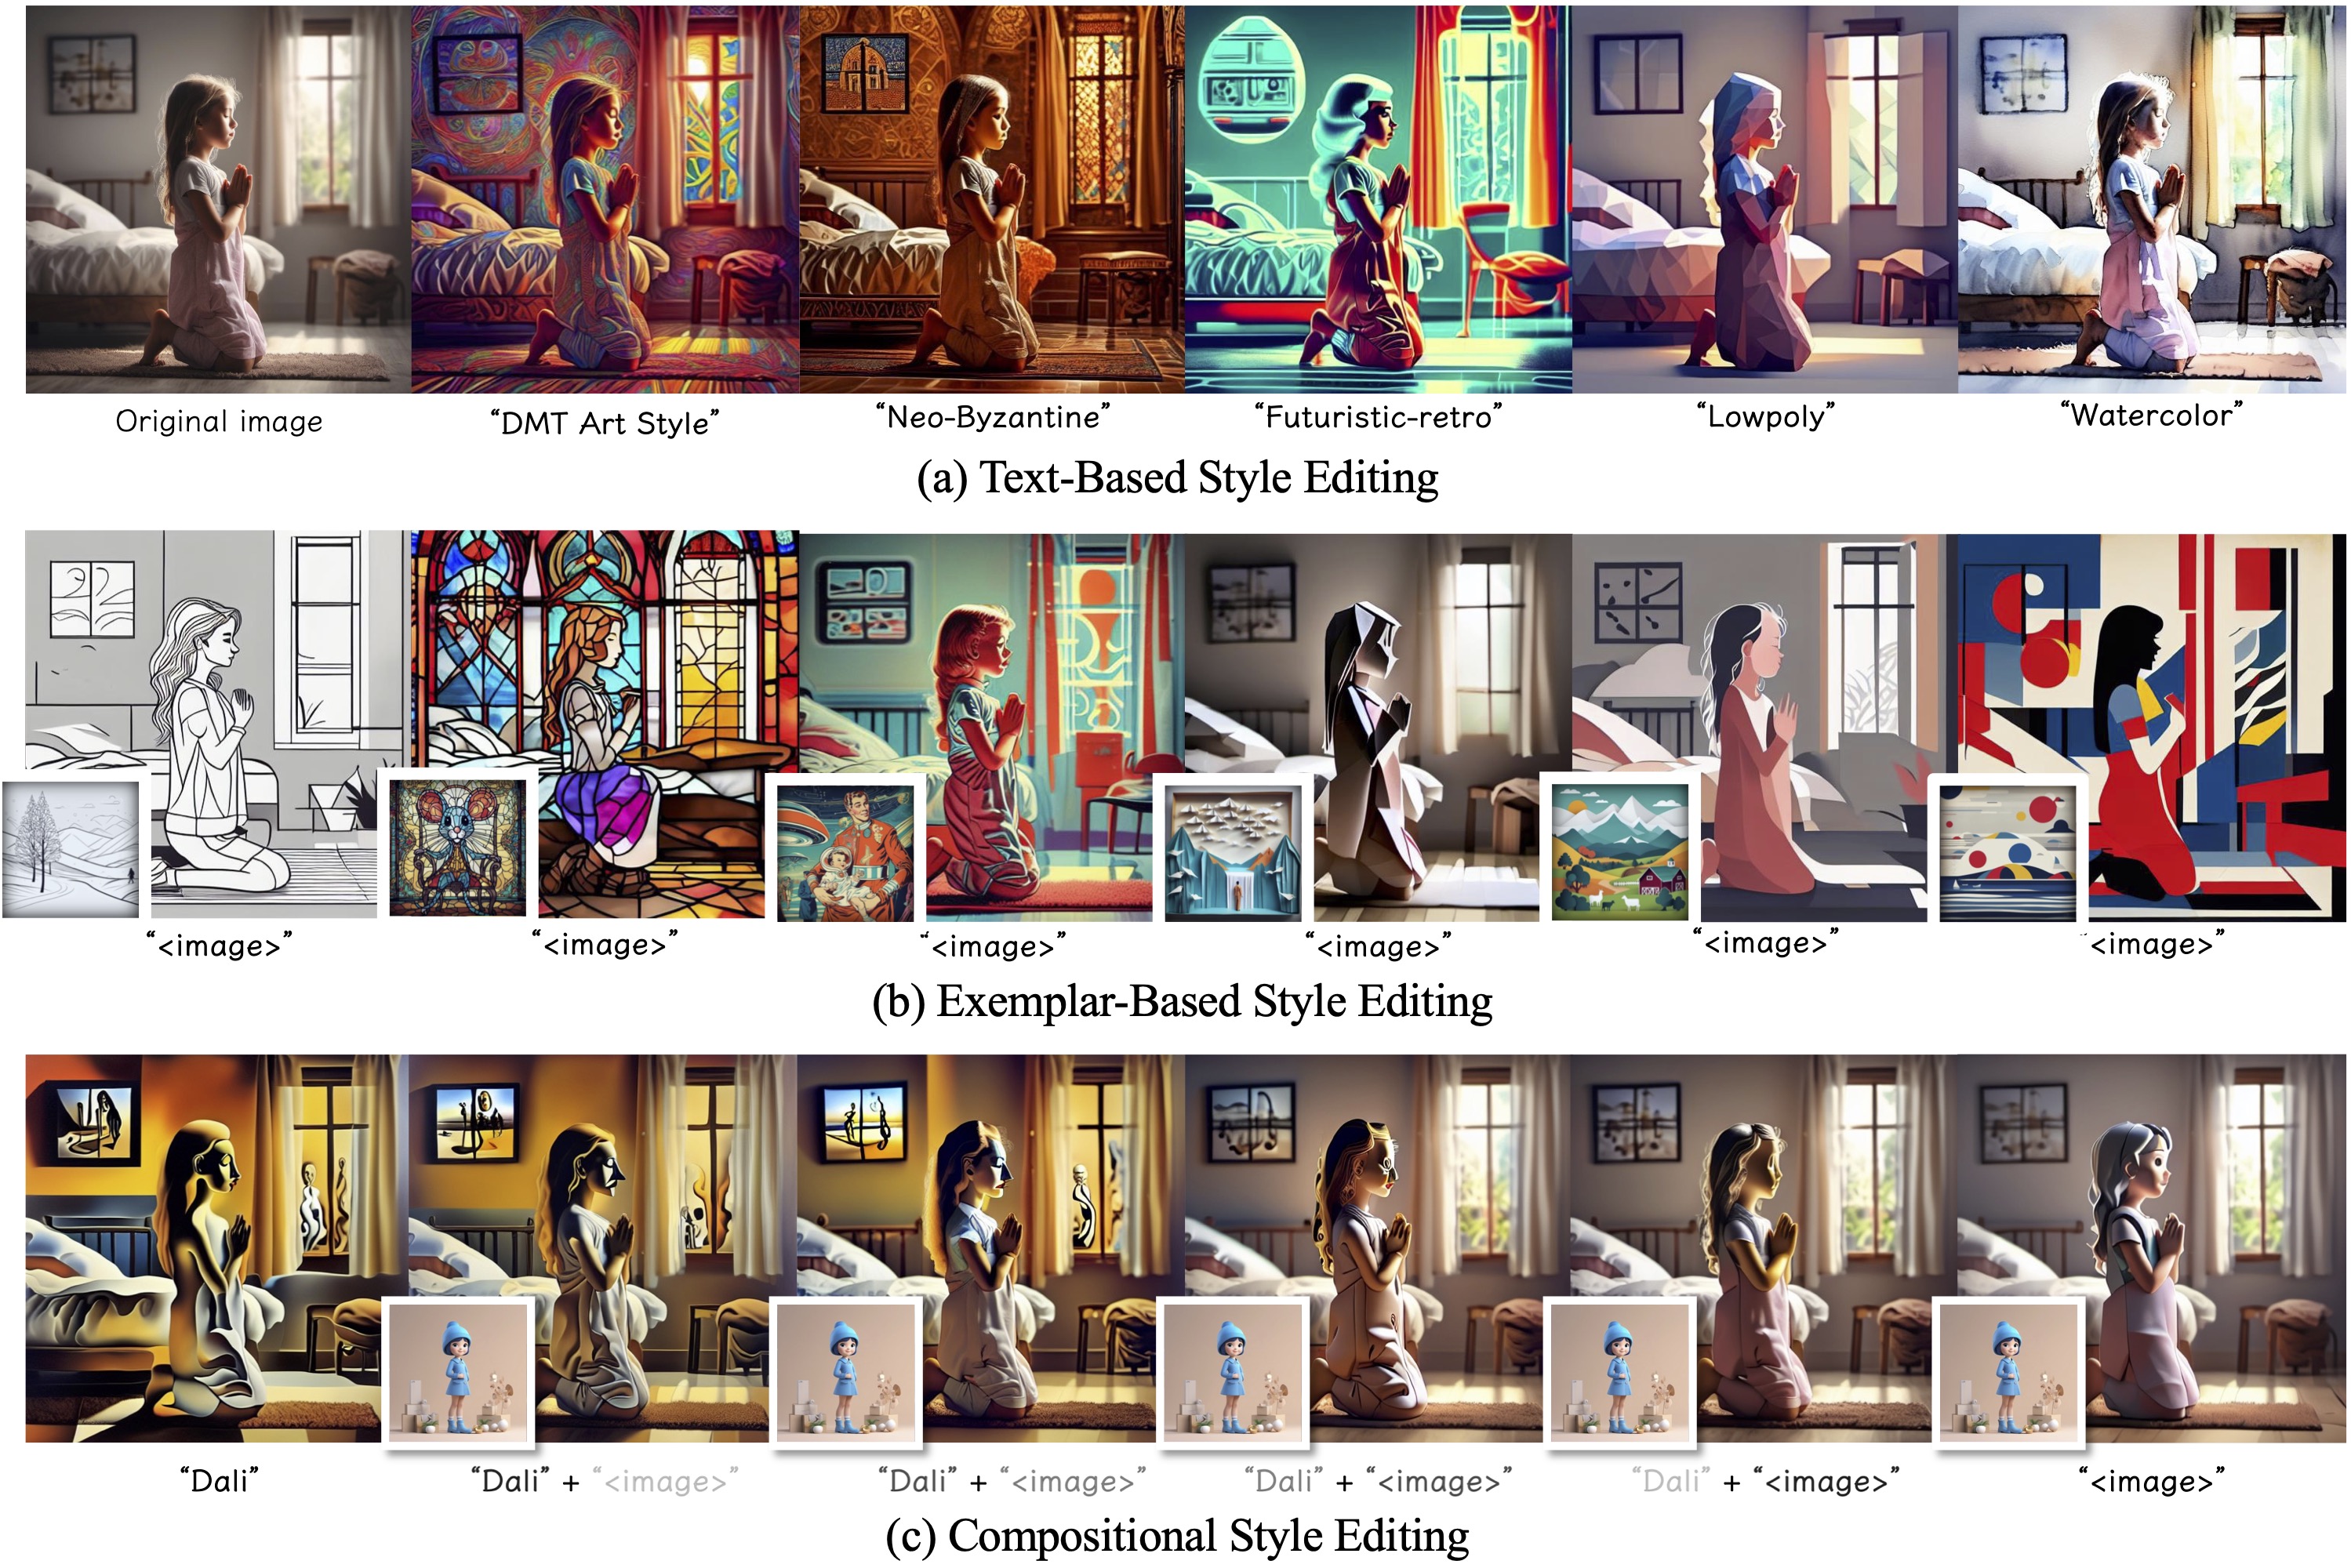
|
|
|
|
## Gallery
|
|
|
|
<table>
|
|
<tr>
|
|
<td><strong>Origin Image</strong><br>Gold Dragon Tuner</td>
|
|
<td><strong>Graffiti Art</strong></td>
|
|
<td><strong>Adorable Kawaii</strong></td>
|
|
<td><strong>game-retro game</strong></td>
|
|
<td><strong>Vincent van Gogh</strong></td>
|
|
</tr>
|
|
<tr>
|
|
<td><img src="../../../asset/images/scedit/tuner_gold_dragon.jpeg" width="240"></td>
|
|
<td><img src="../../../asset/images/stylebooth/graffiti.jpeg" width="240"></td>
|
|
<td><img src="../../../asset/images/stylebooth/kawaii.jpeg" width="240"></td>
|
|
<td><img src="../../../asset/images/stylebooth/retrogame.jpeg" width="240"></td>
|
|
<td><img src="../../../asset/images/stylebooth/vangogh.jpeg" width="240"></td>
|
|
</tr>
|
|
<tr>
|
|
<td><strong>Origin Image</strong></td>
|
|
<td><strong>Lowpoly</strong></td>
|
|
<td><strong>Colored Pencil Art</strong></td>
|
|
<td><strong>Watercolor</strong></td>
|
|
<td><strong>misc-disco</strong></td>
|
|
</tr>
|
|
<tr>
|
|
<td><img src="../../../asset/images/stylebooth/mountain.jpg" width="240"></td>
|
|
<td><img src="../../../asset/images/stylebooth/lowpoly.jpg" width="240"></td>
|
|
<td><img src="../../../asset/images/stylebooth/colorpencil.jpeg" width="240"></td>
|
|
<td><img src="../../../asset/images/stylebooth/watercolor.jpeg" width="240"></td>
|
|
<td><img src="../../../asset/images/stylebooth/disco.jpeg" width="240"></td>
|
|
</tr>
|
|
</table>
|
|
## Features
|
|
|
|
| **Text-Based** | **Exemplar-Based** |
|
|
|:--------------:|:-----------------:|
|
|
| 🪄 | ⏳ |
|
|
|
|
- ✅ indicates support for both training and inference.
|
|
- 🪄 denotes that the model has been published.
|
|
- ⏳ denotes that the module has not been integrated currently.
|
|
- More models will be released in the future.
|
|
|
|
## Run StyleBooth
|
|
- Code implementation: See model configuration and code based on [🪄SCEPTER](https://github.com/modelscope/scepter/blob/main/docs/en/tasks/stylebooth.md).
|
|
|
|
- Demo: Try [🖥️SCEPTER Studio](https://github.com/modelscope/scepter/tree/main?tab=readme-ov-file#%EF%B8%8F-scepter-studio).
|
|
|
|
- Easy run:
|
|
Try the following example script to run StyleBooth modified from [tests/modules/test_diffusion_inference.py](https://github.com/modelscope/scepter/blob/main/tests/modules/test_diffusion_inference.py):
|
|
|
|
```python
|
|
# `pip install scepter>0.0.4` or
|
|
# clone newest SCEPTER and run `PYTHONPATH=./ python <this_script>` at the main branch root.
|
|
import os
|
|
import unittest
|
|
|
|
from PIL import Image
|
|
from torchvision.utils import save_image
|
|
|
|
from scepter.modules.inference.stylebooth_inference import StyleboothInference
|
|
from scepter.modules.utils.config import Config
|
|
from scepter.modules.utils.file_system import FS
|
|
from scepter.modules.utils.logger import get_logger
|
|
|
|
|
|
class DiffusionInferenceTest(unittest.TestCase):
|
|
def setUp(self):
|
|
print(('Testing %s.%s' % (type(self).__name__, self._testMethodName)))
|
|
self.logger = get_logger(name='scepter')
|
|
config_file = 'scepter/methods/studio/scepter_ui.yaml'
|
|
cfg = Config(cfg_file=config_file)
|
|
if 'FILE_SYSTEM' in cfg:
|
|
for fs_info in cfg['FILE_SYSTEM']:
|
|
FS.init_fs_client(fs_info)
|
|
self.tmp_dir = './cache/save_data/diffusion_inference'
|
|
if not os.path.exists(self.tmp_dir):
|
|
os.makedirs(self.tmp_dir)
|
|
|
|
def tearDown(self):
|
|
super().tearDown()
|
|
|
|
# uncomment this line to skip this module.
|
|
# @unittest.skip('')
|
|
def test_stylebooth(self):
|
|
config_file = 'scepter/methods/studio/inference/edit/stylebooth_tb_pro.yaml'
|
|
cfg = Config(cfg_file=config_file)
|
|
diff_infer = StyleboothInference(logger=self.logger)
|
|
diff_infer.init_from_cfg(cfg)
|
|
|
|
output = diff_infer({'prompt': 'Let this image be in the style of sai-lowpoly'},
|
|
style_edit_image=Image.open('asset/images/inpainting_text_ref/ex4_scene_im.jpg'),
|
|
style_guide_scale_text=7.5,
|
|
style_guide_scale_image=1.5)
|
|
save_path = os.path.join(self.tmp_dir,
|
|
'stylebooth_test_lowpoly_cute_dog.png')
|
|
save_image(output['images'], save_path)
|
|
|
|
|
|
if __name__ == '__main__':
|
|
unittest.main()
|
|
```
|
|
|
|
## StyleTuner and De-StyleTuner.
|
|
|
|
### Base I2I Model.
|
|
|
|
For style and de-style tuning, we use a private high-resolution I2I model trained with [InstructPix2Pix dataset](https://instruct-pix2pix.eecs.berkeley.edu/) as base model. However, one can try the same tunning process using this [yaml](https://github.com/modelscope/scepter/blob/main/scepter/methods/edit/edit_512_lora.yaml) based on any other I2I model, such as StyleBooth (shown in this yaml), [InstructPix2Pix](https://github.com/timothybrooks/instruct-pix2pix) or [MagicBrush](https://github.com/OSU-NLP-Group/MagicBrush).
|
|
|
|
### Training Data.
|
|
|
|
Please check the zips for correct format: [De-Text](https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=datasets%2Fdetext.zip), [Image2Hed](https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=datasets%2Fhed_pair.zip), [Image2Depth](https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=datasets%2Fimage2depth.zip), [Depth2Image](https://www.modelscope.cn/api/v1/models/iic/scepter/repo?Revision=master&FilePath=datasets%2Fdepth2image.zip).
|
|
|
|
### Launch.
|
|
|
|
See [code](https://github.com/modelscope/scepter/blob/cbbef4a2da5b66fc33b9f8ece7f2fb4aac9d6e3c/tests/tools/test_train.py#L220) for more information.
|