1.8.0
This commit is contained in:
 noembryo
@@ -100,6 +100,20 @@ Outputs match the stock Load Image node: **IMAGE**, **MASK** (from the alpha cha
|
||||
**Credits:**
|
||||
Built as a much more enhanced version of [Load Image From Path (Enhanced)](https://github.com/Chaoses-Ib/ComfyUI_Ib_CustomNodes#load-image-from-path-enhanced) from [ComfyUI_Ib_CustomNodes](https://github.com/Chaoses-Ib/ComfyUI_Ib_CustomNodes), with parts of the interactive crop UI inspired from [Load Image & Crop](https://github.com/obvpm/comfyui-obvpm#load-image--crop) in [comfyui-obvpm](https://github.com/obvpm/comfyui-obvpm).
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Image Composer
|
||||
|
||||

|
||||
|
||||
Compose several images into ONE image.
|
||||
Images keep their order and relative pixel sizes (natural sizing, never enlarged) and are packed as tightly as possible; rows are chosen automatically.
|
||||
The preview refreshes instantly when an upstream image, crop, rotation or megapixel cap changes; no workflow run needed.
|
||||
|
||||
The inputs are automatically increase, every time you connect a new image loader.
|
||||
|
||||
---
|
||||
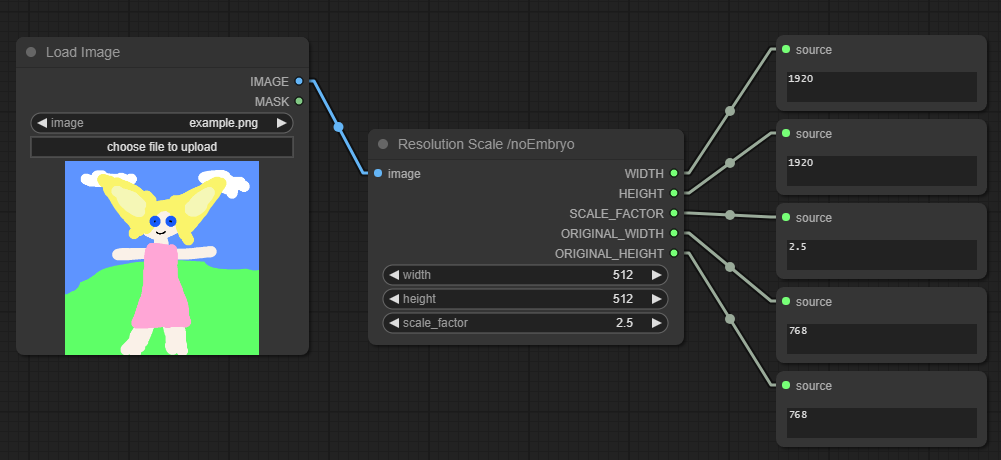
## Resolution Scale
|
||||
|
||||
@@ -143,6 +157,53 @@ No quality loss, like when trying to concatenate encoded videos.
|
||||
- **frame_count**: The total number of frames
|
||||
- **report**: Logging of some of the node's actions
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## H3 Clip Refiner
|
||||
|
||||

|
||||
Inline texture-ratchet correction node for `H3 Motion Context` clips.
|
||||
|
||||
Place this node BETWEEN the sampler (`SamplerCustomAdvanced`) and the `H3 Motion Context Save Latent` node.
|
||||
It operates on the LATENT level (no VAE decode/encode needed for measurement) to fix the "texture ratchet": high-band noise/grain increases monotonically at each join (+4.2% mid-band per join).
|
||||
The statistic is band_ratio = high-band std / total std.
|
||||
Measured across a chain it goes 0.3643 -> 0.3673 -> 0.3702 (monotone increase).
|
||||
|
||||
|
||||
|
||||
- **Inputs**
|
||||
- **latent** gets the generated AV latent from your H3 sampler (SamplerCustomAdvanced output).
|
||||
- **reference_latent** is optional. It gets the reference latent (e.g., first clip) to measure target_ratio from it automatically.
|
||||
If connected, target_ratio is ignored and measured from this latent.
|
||||
|
||||
- **Outputs**
|
||||
- **latent** is the refined latent.
|
||||
- **report**: shows the report of the latent analysis.
|
||||
|
||||
|
||||
|
||||
- **Controls**
|
||||
- **target_ratio** is the ratio to rescale the high-band so the band_ratio matches the target clip (first)
|
||||
- **strength** is how much change it finally produces.
|
||||
- 0 = None
|
||||
- 1.0 = Full
|
||||
- > 1.0 = Overshoot
|
||||
|
||||
1. **Usage**:
|
||||
1. First run: set target_ratio=0.0 (measure mode).
|
||||
The node measures the band_ratio (high-band std / total std) of the video latent and logs it (e.g., "band_ratio=0.3673").
|
||||
The latent passes through unchanged.
|
||||
2. Note the reported band_ratio from the FIRST clip (e.g., 0.3643).
|
||||
3. Subsequent runs: set target_ratio to the first clip's band_ratio (e.g., 0.3643).
|
||||
The node applies match_band to rescale the high-band so the band_ratio matches the target, fixing the texture ratchet.
|
||||
|
||||
|
||||
*TO MAKE IT LESS GRAINY*:
|
||||
If a clip measures at 0.3917, and you want it less grainy, set target_ratio to a LOWER value (e.g., 0.3800).
|
||||
The lower the target_ratio, the more the high-band grain is reduced.
|
||||
|
||||
---
|
||||
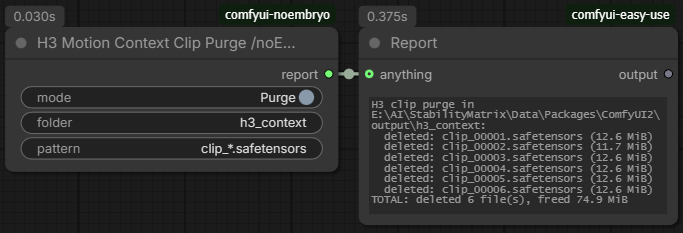
## H3 Motion Context Clip Purge
|
||||
|
||||
@@ -159,6 +220,68 @@ Only files matching the pattern are removed; sub-folders and everything inside t
|
||||
- **Outputs**
|
||||
- **report**: Shows the actions of the node.
|
||||
|
||||
---
|
||||
|
||||
## H3 AV Latent from Video
|
||||
|
||||

|
||||
Encodes a whole video (IMAGE frames + AUDIO) with the MiniMax H3 VAEs into an AV latent that can be saved with `H3 Motion Context Save Latent` and stitched into later generations.
|
||||
|
||||
- **Inputs**
|
||||
- **video_vae** for encoding the video.
|
||||
- **audio_vae** for encoding the audio
|
||||
- **images** The whole video as frames (e.g. from VHS Load Video).
|
||||
Leave un-connected when using the latent input.
|
||||
- **latent** (optional) alternative to images.
|
||||
Accepts either a nested AV latent from `LTXVConcatAVLatent` (its audio stream is used directly), or an already-encoded H3 video LATENT from VAE Encode.
|
||||
A standard [B,C,H,W] latent is wrapped as a one-frame H3 video stream
|
||||
Connect AUDIO separately when it has no audio stream.
|
||||
- **audio** (optional) The video's audio (e.g. from VHS Load Video).
|
||||
Leave un-connected for a silent clip.
|
||||
Ignored when latent already contains an audio stream.
|
||||
|
||||
- **Outputs**
|
||||
- **latent** is the `H3 Motion Context` AV latent
|
||||
- **Controls**
|
||||
- **source_fps** The frame rate of the loaded video.
|
||||
Frames are resampled to H3's native 24 fps by time-based frame picking, so audio stays in sync at any source rate.
|
||||
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## H3 Context Latent Converter
|
||||
|
||||
A utility node that converts an `H3 Motion Context` archive latent (as loaded by `MiniMaxH3MotionContextLoadLatent`, whose 'samples' is a plain list) into the AV latent form that comfy-core's `LTXVSeparateAVLatent` expects (av_latent["samples"].unbind() -> (video, audio)).
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Replace Audio no Re-Encode
|
||||
|
||||

|
||||
A minimal ComfyUI custom node that replaces the audio stream of an existing video file with a new audio track, using ffmpeg's stream-copy mode for the video (`-c:v copy`). The video bitstream is remuxed losslessly and is never decoded/re-encoded, only the container is rewritten with a new audio stream. Requires ffmpeg to be installed and available on PATH.
|
||||
|
||||
- **Input**
|
||||
- **audio**: ComfyUI AUDIO signal (e.g. from Load Audio or a generated audio node) to use as the new audio stream.
|
||||
Ignored if audio_path is set.
|
||||
|
||||
- **Output**
|
||||
- **video_path** returns the path where the video is saved in text.
|
||||
|
||||
- **Controls**
|
||||
- **video_path** Path to the video file whose audio stream will be replaced (e.g. any .mp4/.mov/.mkv on disk).
|
||||
- **filename_prefix** Prefix for the output file name.
|
||||
The result is saved in the ComfyUI output directory as: <prefix>_<video name>_<counter>.<ext>
|
||||
- **audio_codec** How to encode the new audio stream:
|
||||
- aac: re-encode to AAC 192kbps (always used when the audio comes from the audio input)
|
||||
- copy: remux the audio file losslessly, without re-encoding (only meaningful when using the audio_path input)"
|
||||
- **audio_path** Path to an audio file, or a video file, whose audio stream will be extracted, to be used as the new audio stream.
|
||||
If set, it takes priority over the audio input.
|
||||
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
+1
-53
@@ -673,58 +673,6 @@ class H3MotionContextClipStitcher:
|
||||
return final_images, final_audio, frame_count, report
|
||||
|
||||
|
||||
# --- Contrast measurement helpers for inline H3ClipRefiner ---
|
||||
|
||||
def _contrast_measure_luminance(frames):
|
||||
"""Compute per-frame luminance contrast (std of luminance) for [N,H,W,3] frames in 0..1.
|
||||
Returns [N] tensor of contrast values."""
|
||||
# Luminance = 0.2126*R + 0.7152*G + 0.0722*B
|
||||
lum = (frames[..., 0] * 0.2126 + frames[..., 1] * 0.7152 + frames[..., 2] * 0.0722)
|
||||
# Contrast = std of luminance per frame
|
||||
return lum.reshape(lum.shape[0], -1).std(dim=1)
|
||||
|
||||
|
||||
def _contrast_correct_frames(frames, head_contrast, tail_contrast, strength):
|
||||
"""Apply contrast correction to frames to undo the contrast drift.
|
||||
|
||||
The denoiser typically changes contrast from head to tail (usually increases it).
|
||||
We measure the contrast ratio (tail/head) and scale luminance to bring tail
|
||||
contrast back to head level.
|
||||
|
||||
frames: [N,H,W,3] in 0..1
|
||||
head_contrast: mean contrast of first N frames
|
||||
tail_contrast: mean contrast of last N frames
|
||||
strength: 0..1, how much of the correction to apply (1.0 = full correction to head level)
|
||||
Returns corrected frames.
|
||||
"""
|
||||
if head_contrast <= 1e-6 or tail_contrast <= 1e-6:
|
||||
return frames
|
||||
|
||||
# Contrast ratio: tail/head.
|
||||
# ratio > 1 -> contrast increases (degradation), need to reduce
|
||||
# ratio < 1 -> contrast drops, need to boost
|
||||
ratio = tail_contrast / head_contrast
|
||||
|
||||
# Target correction factor: 1/ratio brings tail contrast to head level.
|
||||
# Interpolate between 1.0 (no correction) and 1/ratio (full correction).
|
||||
correction = 1.0 + (1.0 / ratio - 1.0) * strength
|
||||
correction = max(0.5, min(2.0, correction)) # clamp for safety
|
||||
|
||||
# Apply contrast correction in luminance space
|
||||
# Convert to luminance, scale around mean, convert back
|
||||
lum = (frames[..., 0] * 0.2126 + frames[..., 1] * 0.7152 + frames[..., 2] * 0.0722)
|
||||
lum_mean = lum.mean(dim=(1, 2), keepdim=True)
|
||||
lum_corrected = lum_mean + (lum - lum_mean) * correction
|
||||
|
||||
# Reconstruct RGB: preserve chroma by scaling RGB proportionally
|
||||
# This is an approximation - proper way would be Lab space
|
||||
scale = torch.where(lum > 1e-6, lum_corrected / lum, torch.ones_like(lum))
|
||||
scale = scale.unsqueeze(-1)
|
||||
corrected = frames * scale
|
||||
|
||||
return corrected.clamp_(0.0, 1.0)
|
||||
|
||||
|
||||
class H3ClipRefiner:
|
||||
""" Inline texture-ratchet correction node for H3 Motion Context clips.
|
||||
|
||||
@@ -751,7 +699,7 @@ class H3ClipRefiner:
|
||||
match the target band_ratio. Low-frequency structure (scene content) is
|
||||
bit-identical preserved. No VAE decode/encode needed for the correction.
|
||||
|
||||
TO MAKE IT LESS GRAINY: If a clip measures at 0.3917 and you want it less
|
||||
TO MAKE IT LESS GRAINY: If a clip measures at 0.3917, and you want it less
|
||||
grainy, set target_ratio to a LOWER value (e.g., 0.3800). The lower the
|
||||
target_ratio, the more the high-band grain is reduced.
|
||||
"""
|
||||
|
||||
@@ -11,14 +11,14 @@ from .minimax import (H3MotionContextClipStitcher, H3ClipRefiner,
|
||||
H3MotionContextClipPurge, H3AVLatentFromVideo)
|
||||
|
||||
MANIFEST = {"name": "noEmbryo Nodes",
|
||||
"version": (1, 6, 6),
|
||||
"version": (1, 8, 0),
|
||||
"author": "noEmbryo",
|
||||
"project": "https://github.com/noembryo/ComfyUI-noEmbryo",
|
||||
"description": "Nodes for ComfyUI",
|
||||
"license": "MIT",
|
||||
}
|
||||
__author__ = "noEmbryo"
|
||||
__version__ = "1.6.6"
|
||||
__version__ = "1.8.0"
|
||||
|
||||
LISTS_PATH = join(dirname(realpath(__file__)), "TermLists")
|
||||
|
||||
@@ -81,6 +81,9 @@ class JsonPromptLoader:
|
||||
RETURN_NAMES = ("Prompt",)
|
||||
FUNCTION = "run"
|
||||
CATEGORY = "noEmbryo/Prompt"
|
||||
DESCRIPTION = ("A node that can load a `.json` file with `item:prompt` pairs and outputs "
|
||||
"the selected item's prompt, while combining it with a custom prompt.\n"
|
||||
"It can load `.json` files from any directory, not just the node's directory.")
|
||||
|
||||
def run(self, json_path, selected_item, variable, custom_prompt):
|
||||
self.load_data(json_path)
|
||||
|
||||
+1
-1
@@ -12,7 +12,7 @@ limit the output's size in megapixels. \n
|
||||
* "PromptTermList (1-6)" nodes to help with the creation of Prompts. \n
|
||||
* "Auto Save Workflow" can save the current workflow to a .json file automatically. \n
|
||||
"""
|
||||
version = "1.6.7"
|
||||
version = "1.8.0"
|
||||
license = {text = "MIT License"}
|
||||
dependencies = []
|
||||
|
||||
|
||||
Reference in New Issue
Block a user