add new
 smthem
@@ -0,0 +1,262 @@
|
||||
<div align="center">
|
||||
<h1>CSGO: Content-Style Composition in Text-to-Image Generation</h1>
|
||||
|
||||
[**Peng Xing**](https://github.com/xingp-ng)<sup>12*</sup> · [**Haofan Wang**](https://haofanwang.github.io/)<sup>1*</sup> · [**Yanpeng Sun**](https://scholar.google.com.hk/citations?user=a3FI8c4AAAAJ&hl=zh-CN&oi=ao/)<sup>2</sup> · [**Qixun Wang**](https://github.com/wangqixun)<sup>1</sup> · [**Xu Bai**](https://huggingface.co/baymin0220)<sup>1</sup> · [**Hao Ai**](https://github.com/aihao2000)<sup>13</sup> · [**Renyuan Huang**](https://github.com/DannHuang)<sup>14</sup> · [**Zechao Li**](https://zechao-li.github.io/)<sup>2✉</sup>
|
||||
|
||||
<sup>1</sup>InstantX Team · <sup>2</sup>Nanjing University of Science and Technology · <sup>3</sup>Beihang University · <sup>4</sup>Peking University
|
||||
|
||||
<sup>*</sup>equal contributions, <sup>✉</sup>corresponding authors
|
||||
|
||||
<a href='https://csgo-gen.github.io/'><img src='https://img.shields.io/badge/Project-Page-green'></a>
|
||||
<a href='https://arxiv.org/abs/2404.02733'><img src='https://img.shields.io/badge/Technique-Report-red'></a>
|
||||
[](https://huggingface.co/InstantX/CSGO)
|
||||
[](https://huggingface.co/spaces/xingpng/CSGO/)
|
||||
[](https://github.com/instantX-research/CSGO)
|
||||
</div>
|
||||
|
||||
|
||||
## Updates 🔥
|
||||
|
||||
[//]: # (- **`2024/07/19`**: ✨ We support 🎞️ portrait video editing (aka v2v)! More to see [here](assets/docs/changelog/2024-07-19.md).)
|
||||
|
||||
[//]: # (- **`2024/07/17`**: 🍎 We support macOS with Apple Silicon, modified from [jeethu](https://github.com/jeethu)'s PR [#143](https://github.com/KwaiVGI/LivePortrait/pull/143).)
|
||||
|
||||
[//]: # (- **`2024/07/10`**: 💪 We support audio and video concatenating, driving video auto-cropping, and template making to protect privacy. More to see [here](assets/docs/changelog/2024-07-10.md).)
|
||||
|
||||
[//]: # (- **`2024/07/09`**: 🤗 We released the [HuggingFace Space](https://huggingface.co/spaces/KwaiVGI/liveportrait), thanks to the HF team and [Gradio](https://github.com/gradio-app/gradio)!)
|
||||
[//]: # (Continuous updates, stay tuned!)
|
||||
- **`2024/09/04`**: 🔥 We released the gradio code. You can simply configure it and use it directly.
|
||||
- **`2024/09/03`**: 🔥 We released the online demo on [Hugggingface](https://huggingface.co/spaces/xingpng/CSGO/).
|
||||
- **`2024/09/03`**: 🔥 We released the [pre-trained weight](https://huggingface.co/InstantX/CSGO).
|
||||
- **`2024/09/03`**: 🔥 We released the initial version of the inference code.
|
||||
- **`2024/08/30`**: 🔥 We released the technical report on [arXiv](https://arxiv.org/pdf/2408.16766)
|
||||
- **`2024/07/15`**: 🔥 We released the [homepage](https://csgo-gen.github.io).
|
||||
|
||||
## Plan 💪
|
||||
- [x] technical report
|
||||
- [x] inference code
|
||||
- [x] pre-trained weight [4_16]
|
||||
- [x] pre-trained weight [4_32]
|
||||
- [x] online demo
|
||||
- [ ] IMAGStyle dataset
|
||||
- [ ] training code
|
||||
- [ ] more pre-trained weight
|
||||
|
||||
## Introduction 📖
|
||||
This repo, named **CSGO**, contains the official PyTorch implementation of our paper [CSGO: Content-Style Composition in Text-to-Image Generation](https://arxiv.org/pdf/).
|
||||
We are actively updating and improving this repository. If you find any bugs or have suggestions, welcome to raise issues or submit pull requests (PR) 💖.
|
||||
|
||||
## Pipeline 💻
|
||||
<p align="center">
|
||||
<img src="assets/image3_1.jpg">
|
||||
</p>
|
||||
|
||||
## Capabilities 🚅
|
||||
|
||||
🔥 Our CSGO achieves **image-driven style transfer, text-driven stylized synthesis, and text editing-driven stylized synthesis**.
|
||||
|
||||
🔥 For more results, visit our <a href="https://csgo-gen.github.io"><strong>homepage</strong></a> 🔥
|
||||
|
||||
<p align="center">
|
||||
<img src="assets/vis.jpg">
|
||||
</p>
|
||||
|
||||
|
||||
## Getting Started 🏁
|
||||
### 1. Clone the code and prepare the environment
|
||||
```bash
|
||||
git clone https://github.com/instantX-research/CSGO
|
||||
cd CSGO
|
||||
|
||||
# create env using conda
|
||||
conda create -n CSGO python=3.9
|
||||
conda activate CSGO
|
||||
|
||||
# install dependencies with pip
|
||||
# for Linux and Windows users
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
### 2. Download pretrained weights
|
||||
|
||||
The easiest way to download the pretrained weights is from HuggingFace:
|
||||
```bash
|
||||
# first, ensure git-lfs is installed, see: https://docs.github.com/en/repositories/working-with-files/managing-large-files/installing-git-large-file-storage
|
||||
git lfs install
|
||||
# clone and move the weights
|
||||
git clone https://huggingface.co/InstanX/CSGO CSGO
|
||||
```
|
||||
Our method is fully compatible with [SDXL](https://huggingface.co/stabilityai/stable-diffusion-xl-base-1.0), [VAE](https://huggingface.co/madebyollin/sdxl-vae-fp16-fix), [ControlNet](https://huggingface.co/TTPlanet/TTPLanet_SDXL_Controlnet_Tile_Realistic), and [Image Encoder](https://huggingface.co/h94/IP-Adapter/tree/main/sdxl_models/image_encoder).
|
||||
Please download them and place them in the ./base_models folder.
|
||||
|
||||
tips:If you expect to load Controlnet directly using ControlNetPipeline as in CSGO, do the following:
|
||||
```bash
|
||||
git clone https://huggingface.co/TTPlanet/TTPLanet_SDXL_Controlnet_Tile_Realistic
|
||||
mv TTPLanet_SDXL_Controlnet_Tile_Realistic/TTPLANET_Controlnet_Tile_realistic_v2_fp16.safetensors TTPLanet_SDXL_Controlnet_Tile_Realistic/diffusion_pytorch_model.safetensors
|
||||
```
|
||||
### 3. Inference 🚀
|
||||
|
||||
```python
|
||||
import torch
|
||||
from ip_adapter.utils import BLOCKS as BLOCKS
|
||||
from ip_adapter.utils import controlnet_BLOCKS as controlnet_BLOCKS
|
||||
from PIL import Image
|
||||
from diffusers import (
|
||||
AutoencoderKL,
|
||||
ControlNetModel,
|
||||
StableDiffusionXLControlNetPipeline,
|
||||
|
||||
)
|
||||
from ip_adapter import CSGO
|
||||
|
||||
|
||||
device = torch.device("cuda:0" if torch.cuda.is_available() else "cpu")
|
||||
|
||||
base_model_path = "./base_models/stable-diffusion-xl-base-1.0"
|
||||
image_encoder_path = "./base_models/IP-Adapter/sdxl_models/image_encoder"
|
||||
csgo_ckpt = "./CSGO/csgo.bin"
|
||||
pretrained_vae_name_or_path ='./base_models/sdxl-vae-fp16-fix'
|
||||
controlnet_path = "./base_models/TTPLanet_SDXL_Controlnet_Tile_Realistic"
|
||||
weight_dtype = torch.float16
|
||||
|
||||
|
||||
vae = AutoencoderKL.from_pretrained(pretrained_vae_name_or_path,torch_dtype=torch.float16)
|
||||
controlnet = ControlNetModel.from_pretrained(controlnet_path, torch_dtype=torch.float16,use_safetensors=True)
|
||||
pipe = StableDiffusionXLControlNetPipeline.from_pretrained(
|
||||
base_model_path,
|
||||
controlnet=controlnet,
|
||||
torch_dtype=torch.float16,
|
||||
add_watermarker=False,
|
||||
vae=vae
|
||||
)
|
||||
pipe.enable_vae_tiling()
|
||||
|
||||
|
||||
target_content_blocks = BLOCKS['content']
|
||||
target_style_blocks = BLOCKS['style']
|
||||
controlnet_target_content_blocks = controlnet_BLOCKS['content']
|
||||
controlnet_target_style_blocks = controlnet_BLOCKS['style']
|
||||
|
||||
csgo = CSGO(pipe, image_encoder_path, csgo_ckpt, device, num_content_tokens=4,num_style_tokens=32,
|
||||
target_content_blocks=target_content_blocks, target_style_blocks=target_style_blocks,controlnet=False,controlnet_adapter=True,
|
||||
controlnet_target_content_blocks=controlnet_target_content_blocks,
|
||||
controlnet_target_style_blocks=controlnet_target_style_blocks,
|
||||
content_model_resampler=True,
|
||||
style_model_resampler=True,
|
||||
load_controlnet=False,
|
||||
|
||||
)
|
||||
|
||||
style_name = 'img_0.png'
|
||||
content_name = 'img_0.png'
|
||||
style_image = "../assets/{}".format(style_name)
|
||||
content_image = Image.open('../assets/{}'.format(content_name)).convert('RGB')
|
||||
|
||||
caption ='a small house with a sheep statue on top of it'
|
||||
|
||||
num_sample=4
|
||||
|
||||
#image-driven style transfer
|
||||
images = csgo.generate(pil_content_image= content_image, pil_style_image=style_image,
|
||||
prompt=caption,
|
||||
negative_prompt= "text, watermark, lowres, low quality, worst quality, deformed, glitch, low contrast, noisy, saturation, blurry",
|
||||
content_scale=1.0,
|
||||
style_scale=1.0,
|
||||
guidance_scale=10,
|
||||
num_images_per_prompt=num_sample,
|
||||
num_samples=1,
|
||||
num_inference_steps=50,
|
||||
seed=42,
|
||||
image=content_image.convert('RGB'),
|
||||
controlnet_conditioning_scale=0.6,
|
||||
)
|
||||
|
||||
#text-driven stylized synthesis
|
||||
caption='a cat'
|
||||
images = csgo.generate(pil_content_image= content_image, pil_style_image=style_image,
|
||||
prompt=caption,
|
||||
negative_prompt= "text, watermark, lowres, low quality, worst quality, deformed, glitch, low contrast, noisy, saturation, blurry",
|
||||
content_scale=1.0,
|
||||
style_scale=1.0,
|
||||
guidance_scale=10,
|
||||
num_images_per_prompt=num_sample,
|
||||
num_samples=1,
|
||||
num_inference_steps=50,
|
||||
seed=42,
|
||||
image=content_image.convert('RGB'),
|
||||
controlnet_conditioning_scale=0.01,
|
||||
)
|
||||
|
||||
#text editing-driven stylized synthesis
|
||||
caption='a small house'
|
||||
images = csgo.generate(pil_content_image= content_image, pil_style_image=style_image,
|
||||
prompt=caption,
|
||||
negative_prompt= "text, watermark, lowres, low quality, worst quality, deformed, glitch, low contrast, noisy, saturation, blurry",
|
||||
content_scale=1.0,
|
||||
style_scale=1.0,
|
||||
guidance_scale=10,
|
||||
num_images_per_prompt=num_sample,
|
||||
num_samples=1,
|
||||
num_inference_steps=50,
|
||||
seed=42,
|
||||
image=content_image.convert('RGB'),
|
||||
controlnet_conditioning_scale=0.4,
|
||||
)
|
||||
```
|
||||
### 4 Gradio interface ⚙️
|
||||
|
||||
We also provide a Gradio <a href='https://github.com/gradio-app/gradio'><img src='https://img.shields.io/github/stars/gradio-app/gradio'></a> interface for a better experience, just run by:
|
||||
|
||||
```bash
|
||||
# For Linux and Windows users (and macOS)
|
||||
python gradio/app.py
|
||||
```
|
||||
If you don't have the resources to configure it, we provide an online [demo](https://huggingface.co/spaces/xingpng/CSGO/).
|
||||
## Demos
|
||||
<p align="center">
|
||||
<br>
|
||||
🔥 For more results, visit our <a href="https://csgo-gen.github.io"><strong>homepage</strong></a> 🔥
|
||||
</p>
|
||||
|
||||
### Content-Style Composition
|
||||
<p align="center">
|
||||
<img src="assets/page1.png">
|
||||
</p>
|
||||
|
||||
<p align="center">
|
||||
<img src="assets/page4.png">
|
||||
</p>
|
||||
|
||||
### Cycle Translation
|
||||
<p align="center">
|
||||
<img src="assets/page8.png">
|
||||
</p>
|
||||
|
||||
### Text-Driven Style Synthesis
|
||||
<p align="center">
|
||||
<img src="assets/page10.png">
|
||||
</p>
|
||||
|
||||
### Text Editing-Driven Style Synthesis
|
||||
<p align="center">
|
||||
<img src="assets/page11.jpg">
|
||||
</p>
|
||||
|
||||
## Star History
|
||||
[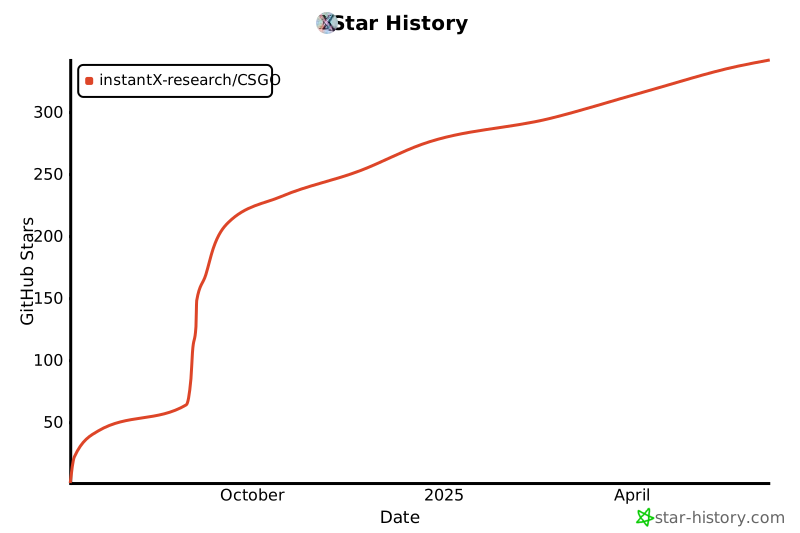](https://star-history.com/#instantX-research/CSGO&Date)
|
||||
|
||||
|
||||
|
||||
## Acknowledgements
|
||||
This project is developed by InstantX Team, all copyright reserved.
|
||||
|
||||
## Citation 💖
|
||||
If you find CSGO useful for your research, welcome to 🌟 this repo and cite our work using the following BibTeX:
|
||||
```bibtex
|
||||
@article{xing2024csgo,
|
||||
title={CSGO: Content-Style Composition in Text-to-Image Generation},
|
||||
author={Peng Xing and Haofan Wang and Yanpeng Sun and Qixun Wang and Xu Bai and Hao Ai and Renyuan Huang and Zechao Li},
|
||||
year={2024},
|
||||
journal = {arXiv 2408.16766},
|
||||
}
|
||||
```
|
||||

|
After Width: | Height: | Size: 1000 KiB |

|
After Width: | Height: | Size: 502 KiB |

|
After Width: | Height: | Size: 551 KiB |

|
After Width: | Height: | Size: 790 KiB |

|
After Width: | Height: | Size: 959 KiB |

|
After Width: | Height: | Size: 2.0 MiB |

|
After Width: | Height: | Size: 10 MiB |

|
After Width: | Height: | Size: 8.5 MiB |

|
After Width: | Height: | Size: 4.4 MiB |

|
After Width: | Height: | Size: 8.9 MiB |

|
After Width: | Height: | Size: 4.4 MiB |
@@ -0,0 +1,343 @@
|
||||
import sys
|
||||
# sys.path.append("../")
|
||||
sys.path.append("./")
|
||||
import gradio as gr
|
||||
import torch
|
||||
from ip_adapter.utils import BLOCKS as BLOCKS
|
||||
from ip_adapter.utils import controlnet_BLOCKS as controlnet_BLOCKS
|
||||
from ip_adapter.utils import resize_content
|
||||
import cv2
|
||||
import numpy as np
|
||||
import random
|
||||
from PIL import Image
|
||||
from transformers import AutoImageProcessor, AutoModel
|
||||
from diffusers import (
|
||||
AutoencoderKL,
|
||||
ControlNetModel,
|
||||
StableDiffusionXLControlNetPipeline,
|
||||
|
||||
)
|
||||
from ip_adapter import CSGO
|
||||
from transformers import BlipProcessor, BlipForConditionalGeneration
|
||||
|
||||
device = torch.device("cuda:0" if torch.cuda.is_available() else "cpu")
|
||||
|
||||
base_model_path = "stabilityai/stable-diffusion-xl-base-1.0"
|
||||
image_encoder_path = "h94/IP-Adapter/sdxl_models/image_encoder"
|
||||
csgo_ckpt ='InstantX/CSGO/csgo_4_32.bin'
|
||||
pretrained_vae_name_or_path ='madebyollin/sdxl-vae-fp16-fix'
|
||||
controlnet_path = "TTPlanet/TTPLanet_SDXL_Controlnet_Tile_Realistic"
|
||||
weight_dtype = torch.float16
|
||||
|
||||
|
||||
|
||||
|
||||
vae = AutoencoderKL.from_pretrained(pretrained_vae_name_or_path,torch_dtype=torch.float16)
|
||||
controlnet = ControlNetModel.from_pretrained(controlnet_path, torch_dtype=torch.float16,use_safetensors=True)
|
||||
pipe = StableDiffusionXLControlNetPipeline.from_pretrained(
|
||||
base_model_path,
|
||||
controlnet=controlnet,
|
||||
torch_dtype=torch.float16,
|
||||
add_watermarker=False,
|
||||
vae=vae
|
||||
)
|
||||
pipe.enable_vae_tiling()
|
||||
|
||||
|
||||
target_content_blocks = BLOCKS['content']
|
||||
target_style_blocks = BLOCKS['style']
|
||||
controlnet_target_content_blocks = controlnet_BLOCKS['content']
|
||||
controlnet_target_style_blocks = controlnet_BLOCKS['style']
|
||||
|
||||
|
||||
|
||||
MAX_SEED = np.iinfo(np.int32).max
|
||||
|
||||
def randomize_seed_fn(seed: int, randomize_seed: bool) -> int:
|
||||
if randomize_seed:
|
||||
seed = random.randint(0, MAX_SEED)
|
||||
return seed
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
def get_example():
|
||||
case = [
|
||||
[
|
||||
"./assets/img_0.png",
|
||||
'./assets/img_1.png',
|
||||
"Image-Driven Style Transfer",
|
||||
"there is a small house with a sheep statue on top of it",
|
||||
0.6,
|
||||
1.0,
|
||||
],
|
||||
[
|
||||
None,
|
||||
'./assets/img_1.png',
|
||||
"Text-Driven Style Synthesis",
|
||||
"a cat",
|
||||
0.01,1.0
|
||||
],
|
||||
[
|
||||
None,
|
||||
'./assets/img_2.png',
|
||||
"Text-Driven Style Synthesis",
|
||||
"a building",
|
||||
0.01, 1.0
|
||||
],
|
||||
[
|
||||
"./assets/img_0.png",
|
||||
'./assets/img_1.png',
|
||||
"Text Edit-Driven Style Synthesis",
|
||||
"there is a small house",
|
||||
0.4,
|
||||
1.0
|
||||
],
|
||||
]
|
||||
return case
|
||||
|
||||
|
||||
def run_for_examples(content_image_pil,style_image_pil,target, prompt, scale_c, scale_s):
|
||||
return create_image(
|
||||
content_image_pil=content_image_pil,
|
||||
style_image_pil=style_image_pil,
|
||||
prompt=prompt,
|
||||
scale_c=scale_c,
|
||||
scale_s=scale_s,
|
||||
guidance_scale=7.0,
|
||||
num_samples=3,
|
||||
num_inference_steps=50,
|
||||
seed=42,
|
||||
target=target,
|
||||
)
|
||||
def randomize_seed_fn(seed: int, randomize_seed: bool) -> int:
|
||||
if randomize_seed:
|
||||
seed = random.randint(0, MAX_SEED)
|
||||
return seed
|
||||
|
||||
def image_grid(imgs, rows, cols):
|
||||
assert len(imgs) == rows * cols
|
||||
|
||||
w, h = imgs[0].size
|
||||
grid = Image.new('RGB', size=(cols * w, rows * h))
|
||||
grid_w, grid_h = grid.size
|
||||
|
||||
for i, img in enumerate(imgs):
|
||||
grid.paste(img, box=(i % cols * w, i // cols * h))
|
||||
return grid
|
||||
def create_image(content_image_pil,
|
||||
style_image_pil,
|
||||
prompt,
|
||||
scale_c,
|
||||
scale_s,
|
||||
guidance_scale,
|
||||
num_samples,
|
||||
num_inference_steps,
|
||||
seed,
|
||||
target="Image-Driven Style Transfer",
|
||||
):
|
||||
|
||||
|
||||
csgo = CSGO(pipe, image_encoder_path, csgo_ckpt, device, num_content_tokens=4, num_style_tokens=32,
|
||||
target_content_blocks=target_content_blocks, target_style_blocks=target_style_blocks,
|
||||
controlnet_adapter=True,
|
||||
controlnet_target_content_blocks=controlnet_target_content_blocks,
|
||||
controlnet_target_style_blocks=controlnet_target_style_blocks,
|
||||
content_model_resampler=True,
|
||||
style_model_resampler=True,
|
||||
)
|
||||
|
||||
|
||||
if content_image_pil is None:
|
||||
content_image_pil = Image.fromarray(
|
||||
np.zeros((1024, 1024, 3), dtype=np.uint8)).convert('RGB')
|
||||
|
||||
if prompt is None:
|
||||
blip_processor = BlipProcessor.from_pretrained("Salesforce/blip-image-captioning-large")
|
||||
blip_model = BlipForConditionalGeneration.from_pretrained("Salesforce/blip-image-captioning-large").to(device)
|
||||
with torch.no_grad():
|
||||
inputs = blip_processor(content_image_pil, return_tensors="pt").to(device)
|
||||
out = blip_model.generate(**inputs)
|
||||
prompt = blip_processor.decode(out[0], skip_special_tokens=True)
|
||||
width, height, content_image = resize_content(content_image_pil)
|
||||
style_image = style_image_pil
|
||||
neg_content_prompt='text, watermark, lowres, low quality, worst quality, deformed, glitch, low contrast, noisy, saturation, blurry'
|
||||
if target =="Image-Driven Style Transfer":
|
||||
with torch.no_grad():
|
||||
images = csgo.generate(pil_content_image=content_image, pil_style_image=style_image,
|
||||
prompt=prompt,
|
||||
negative_prompt=neg_content_prompt,
|
||||
height=height,
|
||||
width=width,
|
||||
content_scale=1.0,
|
||||
style_scale=scale_s,
|
||||
guidance_scale=guidance_scale,
|
||||
num_images_per_prompt=num_samples,
|
||||
num_inference_steps=num_inference_steps,
|
||||
num_samples=1,
|
||||
seed=seed,
|
||||
image=content_image.convert('RGB'),
|
||||
controlnet_conditioning_scale=scale_c,
|
||||
)
|
||||
|
||||
elif target =="Text-Driven Style Synthesis":
|
||||
content_image = Image.fromarray(
|
||||
np.zeros((1024, 1024, 3), dtype=np.uint8)).convert('RGB')
|
||||
with torch.no_grad():
|
||||
images = csgo.generate(pil_content_image=content_image, pil_style_image=style_image,
|
||||
prompt=prompt,
|
||||
negative_prompt="text, watermark, lowres, low quality, worst quality, deformed, glitch, low contrast, noisy, saturation, blurry",
|
||||
height=height,
|
||||
width=width,
|
||||
content_scale=0.5,
|
||||
style_scale=scale_s,
|
||||
guidance_scale=7,
|
||||
num_images_per_prompt=num_samples,
|
||||
num_inference_steps=num_inference_steps,
|
||||
num_samples=1,
|
||||
seed=42,
|
||||
image=content_image.convert('RGB'),
|
||||
controlnet_conditioning_scale=scale_c,
|
||||
)
|
||||
elif target =="Text Edit-Driven Style Synthesis":
|
||||
|
||||
with torch.no_grad():
|
||||
images = csgo.generate(pil_content_image=content_image, pil_style_image=style_image,
|
||||
prompt=prompt,
|
||||
negative_prompt=neg_content_prompt,
|
||||
height=height,
|
||||
width=width,
|
||||
content_scale=1.0,
|
||||
style_scale=scale_s,
|
||||
guidance_scale=guidance_scale,
|
||||
num_images_per_prompt=num_samples,
|
||||
num_inference_steps=num_inference_steps,
|
||||
num_samples=1,
|
||||
seed=seed,
|
||||
image=content_image.convert('RGB'),
|
||||
controlnet_conditioning_scale=scale_c,
|
||||
)
|
||||
|
||||
return [image_grid(images, 1, num_samples)]
|
||||
|
||||
|
||||
def pil_to_cv2(image_pil):
|
||||
image_np = np.array(image_pil)
|
||||
image_cv2 = cv2.cvtColor(image_np, cv2.COLOR_RGB2BGR)
|
||||
return image_cv2
|
||||
|
||||
|
||||
# Description
|
||||
title = r"""
|
||||
<h1 align="center">CSGO: Content-Style Composition in Text-to-Image Generation</h1>
|
||||
"""
|
||||
|
||||
description = r"""
|
||||
<b>Official 🤗 Gradio demo</b> for <a href='https://github.com/instantX-research/CSGO' target='_blank'><b>CSGO: Content-Style Composition in Text-to-Image Generation</b></a>.<br>
|
||||
How to use:<br>
|
||||
1. Upload a content image if you want to use image-driven style transfer.
|
||||
2. Upload a style image.
|
||||
3. Sets the type of task to perform, by default image-driven style transfer is performed. Options are <b>Image-driven style transfer, Text-driven style synthesis, and Text editing-driven style synthesis<b>.
|
||||
4. <b>If you choose a text-driven task, enter your desired prompt<b>.
|
||||
5.If you don't provide a prompt, the default is to use the BLIP model to generate the caption.
|
||||
6. Click the <b>Submit</b> button to begin customization.
|
||||
7. Share your stylized photo with your friends and enjoy! 😊
|
||||
|
||||
Advanced usage:<br>
|
||||
1. Click advanced options.
|
||||
2. Choose different guidance and steps.
|
||||
"""
|
||||
|
||||
article = r"""
|
||||
---
|
||||
📝 **Tips**
|
||||
In CSGO, the more accurate the text prompts for content images, the better the content retention.
|
||||
Text-driven style synthesis and text-edit-driven style synthesis are expected to be more stable in the next release.
|
||||
---
|
||||
📝 **Citation**
|
||||
<br>
|
||||
If our work is helpful for your research or applications, please cite us via:
|
||||
```bibtex
|
||||
@article{xing2024csgo,
|
||||
title={CSGO: Content-Style Composition in Text-to-Image Generation},
|
||||
author={Peng Xing and Haofan Wang and Yanpeng Sun and Qixun Wang and Xu Bai and Hao Ai and Renyuan Huang and Zechao Li},
|
||||
year={2024},
|
||||
journal = {arXiv 2408.16766},
|
||||
}
|
||||
```
|
||||
📧 **Contact**
|
||||
<br>
|
||||
If you have any questions, please feel free to open an issue or directly reach us out at <b>xingp_ng@njust.edu.cn</b>.
|
||||
"""
|
||||
|
||||
block = gr.Blocks(css="footer {visibility: hidden}").queue(max_size=10, api_open=False)
|
||||
with block:
|
||||
# description
|
||||
gr.Markdown(title)
|
||||
gr.Markdown(description)
|
||||
|
||||
with gr.Tabs():
|
||||
with gr.Row():
|
||||
with gr.Column():
|
||||
with gr.Row():
|
||||
with gr.Column():
|
||||
content_image_pil = gr.Image(label="Content Image (optional)", type='pil')
|
||||
style_image_pil = gr.Image(label="Style Image", type='pil')
|
||||
|
||||
target = gr.Radio(["Image-Driven Style Transfer", "Text-Driven Style Synthesis", "Text Edit-Driven Style Synthesis"],
|
||||
value="Image-Driven Style Transfer",
|
||||
label="task")
|
||||
|
||||
prompt = gr.Textbox(label="Prompt",
|
||||
value="there is a small house with a sheep statue on top of it")
|
||||
|
||||
|
||||
scale_c = gr.Slider(minimum=0, maximum=2.0, step=0.01, value=0.6, label="Content Scale")
|
||||
scale_s = gr.Slider(minimum=0, maximum=2.0, step=0.01, value=1.0, label="Style Scale")
|
||||
with gr.Accordion(open=False, label="Advanced Options"):
|
||||
|
||||
guidance_scale = gr.Slider(minimum=1, maximum=15.0, step=0.01, value=7.0, label="guidance scale")
|
||||
num_samples = gr.Slider(minimum=1, maximum=4.0, step=1.0, value=1.0, label="num samples")
|
||||
num_inference_steps = gr.Slider(minimum=5, maximum=100.0, step=1.0, value=50,
|
||||
label="num inference steps")
|
||||
seed = gr.Slider(minimum=-1000000, maximum=1000000, value=1, step=1, label="Seed Value")
|
||||
randomize_seed = gr.Checkbox(label="Randomize seed", value=True)
|
||||
|
||||
generate_button = gr.Button("Generate Image")
|
||||
|
||||
with gr.Column():
|
||||
generated_image = gr.Gallery(label="Generated Image")
|
||||
|
||||
generate_button.click(
|
||||
fn=randomize_seed_fn,
|
||||
inputs=[seed, randomize_seed],
|
||||
outputs=seed,
|
||||
queue=False,
|
||||
api_name=False,
|
||||
).then(
|
||||
fn=create_image,
|
||||
inputs=[content_image_pil,
|
||||
style_image_pil,
|
||||
prompt,
|
||||
|
||||
scale_c,
|
||||
scale_s,
|
||||
guidance_scale,
|
||||
num_samples,
|
||||
num_inference_steps,
|
||||
seed,
|
||||
target,],
|
||||
outputs=[generated_image])
|
||||
|
||||
gr.Examples(
|
||||
examples=get_example(),
|
||||
inputs=[content_image_pil,style_image_pil,target, prompt, scale_c, scale_s],
|
||||
fn=run_for_examples,
|
||||
outputs=[generated_image],
|
||||
cache_examples=True,
|
||||
)
|
||||
|
||||
gr.Markdown(article)
|
||||
|
||||
block.launch(server_name="0.0.0.0", server_port=1234)
|
||||

|
After Width: | Height: | Size: 502 KiB |

|
After Width: | Height: | Size: 551 KiB |

|
After Width: | Height: | Size: 790 KiB |
@@ -0,0 +1,18 @@
|
||||
diffusers==0.25.1
|
||||
torch==2.0.1
|
||||
torchaudio==2.0.2
|
||||
torchvision==0.15.2
|
||||
transformers==4.40.2
|
||||
accelerate
|
||||
safetensors
|
||||
einops
|
||||
spaces==0.19.4
|
||||
omegaconf
|
||||
peft
|
||||
huggingface-hub==0.24.5
|
||||
opencv-python
|
||||
insightface
|
||||
gradio
|
||||
controlnet_aux
|
||||
gdown
|
||||
peft
|
||||
@@ -0,0 +1,86 @@
|
||||
import os
|
||||
os.environ['HF_ENDPOINT']='https://hf-mirror.com'
|
||||
import torch
|
||||
from ip_adapter.utils import BLOCKS as BLOCKS
|
||||
from ip_adapter.utils import controlnet_BLOCKS as controlnet_BLOCKS
|
||||
from ip_adapter.utils import resize_content
|
||||
import cv2
|
||||
from PIL import Image
|
||||
from transformers import AutoImageProcessor, AutoModel
|
||||
from diffusers import (
|
||||
AutoencoderKL,
|
||||
ControlNetModel,
|
||||
StableDiffusionXLControlNetPipeline,
|
||||
|
||||
)
|
||||
from ip_adapter import CSGO
|
||||
from transformers import BlipProcessor, BlipForConditionalGeneration
|
||||
|
||||
device = torch.device("cuda:1" if torch.cuda.is_available() else "cpu")
|
||||
|
||||
base_model_path = "../../../base_models/stable-diffusion-xl-base-1.0"
|
||||
image_encoder_path = "../../../base_models/IP-Adapter/sdxl_models/image_encoder"
|
||||
csgo_ckpt = "/share2/xingpeng/DATA/blora/outputs/content_style_checkpoints_2/base_train_free_controlnet_S12_alldata_C_0_S_I_zero2_style_res_32_content_res4_drop/checkpoint-220000/ip_adapter.bin"
|
||||
pretrained_vae_name_or_path ='../../../base_models/sdxl-vae-fp16-fix'
|
||||
controlnet_path = "../../../base_models/TTPLanet_SDXL_Controlnet_Tile_Realistic"
|
||||
weight_dtype = torch.float16
|
||||
|
||||
blip_processor = BlipProcessor.from_pretrained("Salesforce/blip-image-captioning-large")
|
||||
blip_model = BlipForConditionalGeneration.from_pretrained("Salesforce/blip-image-captioning-large").to(device)
|
||||
|
||||
|
||||
vae = AutoencoderKL.from_pretrained(pretrained_vae_name_or_path,torch_dtype=torch.float16)
|
||||
controlnet = ControlNetModel.from_pretrained(controlnet_path, torch_dtype=torch.float16,use_safetensors=True)
|
||||
pipe = StableDiffusionXLControlNetPipeline.from_pretrained(
|
||||
base_model_path,
|
||||
controlnet=controlnet,
|
||||
torch_dtype=torch.float16,
|
||||
add_watermarker=False,
|
||||
vae=vae
|
||||
)
|
||||
pipe.enable_vae_tiling()
|
||||
|
||||
|
||||
target_content_blocks = BLOCKS['content']
|
||||
target_style_blocks = BLOCKS['style']
|
||||
controlnet_target_content_blocks = controlnet_BLOCKS['content']
|
||||
controlnet_target_style_blocks = controlnet_BLOCKS['style']
|
||||
|
||||
csgo = CSGO(pipe, image_encoder_path, csgo_ckpt, device, num_content_tokens=4,num_style_tokens=32,
|
||||
target_content_blocks=target_content_blocks, target_style_blocks=target_style_blocks,controlnet_adapter=True,
|
||||
controlnet_target_content_blocks=controlnet_target_content_blocks,
|
||||
controlnet_target_style_blocks=controlnet_target_style_blocks,
|
||||
content_model_resampler=True,
|
||||
style_model_resampler=True,
|
||||
)
|
||||
|
||||
style_name = 'img_1.png'
|
||||
content_name = 'img_0.png'
|
||||
style_image = Image.open("../assets/{}".format(style_name)).convert('RGB')
|
||||
content_image = Image.open('../assets/{}'.format(content_name)).convert('RGB')
|
||||
|
||||
|
||||
with torch.no_grad():
|
||||
inputs = blip_processor(content_image, return_tensors="pt").to(device)
|
||||
out = blip_model.generate(**inputs)
|
||||
caption = blip_processor.decode(out[0], skip_special_tokens=True)
|
||||
|
||||
num_sample=1
|
||||
|
||||
width,height,content_image = resize_content(content_image)
|
||||
images = csgo.generate(pil_content_image= content_image, pil_style_image=style_image,
|
||||
prompt=caption,
|
||||
negative_prompt= "text, watermark, lowres, low quality, worst quality, deformed, glitch, low contrast, noisy, saturation, blurry",
|
||||
height=height,
|
||||
width=width,
|
||||
content_scale=0.5,
|
||||
style_scale=1.0,
|
||||
guidance_scale=10,
|
||||
num_images_per_prompt=num_sample,
|
||||
num_samples=1,
|
||||
num_inference_steps=50,
|
||||
seed=42,
|
||||
image=content_image.convert('RGB'),
|
||||
controlnet_conditioning_scale=0.6,
|
||||
)
|
||||
images[0].save("../assets/content_img_0_style_imag_1.png")
|
||||
@@ -0,0 +1,10 @@
|
||||
from .ip_adapter import IPAdapter, IPAdapterPlus, IPAdapterPlusXL, IPAdapterXL, IPAdapterFull,IPAdapterXL_CS,IPAdapter_CS
|
||||
from .ip_adapter import CSGO
|
||||
__all__ = [
|
||||
"IPAdapter",
|
||||
"IPAdapterPlus",
|
||||
"IPAdapterPlusXL",
|
||||
"IPAdapterXL",
|
||||
"CSGO"
|
||||
"IPAdapterFull",
|
||||
]
|
||||
@@ -0,0 +1,754 @@
|
||||
# modified from https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/attention_processor.py
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
|
||||
|
||||
class AttnProcessor(nn.Module):
|
||||
r"""
|
||||
Default processor for performing attention-related computations.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
hidden_size=None,
|
||||
cross_attention_dim=None,
|
||||
save_in_unet='down',
|
||||
atten_control=None,
|
||||
):
|
||||
super().__init__()
|
||||
self.atten_control = atten_control
|
||||
self.save_in_unet = save_in_unet
|
||||
|
||||
def __call__(
|
||||
self,
|
||||
attn,
|
||||
hidden_states,
|
||||
encoder_hidden_states=None,
|
||||
attention_mask=None,
|
||||
temb=None,
|
||||
):
|
||||
residual = hidden_states
|
||||
|
||||
if attn.spatial_norm is not None:
|
||||
hidden_states = attn.spatial_norm(hidden_states, temb)
|
||||
|
||||
input_ndim = hidden_states.ndim
|
||||
|
||||
if input_ndim == 4:
|
||||
batch_size, channel, height, width = hidden_states.shape
|
||||
hidden_states = hidden_states.view(batch_size, channel, height * width).transpose(1, 2)
|
||||
|
||||
batch_size, sequence_length, _ = (
|
||||
hidden_states.shape if encoder_hidden_states is None else encoder_hidden_states.shape
|
||||
)
|
||||
attention_mask = attn.prepare_attention_mask(attention_mask, sequence_length, batch_size)
|
||||
|
||||
if attn.group_norm is not None:
|
||||
hidden_states = attn.group_norm(hidden_states.transpose(1, 2)).transpose(1, 2)
|
||||
|
||||
query = attn.to_q(hidden_states)
|
||||
|
||||
if encoder_hidden_states is None:
|
||||
encoder_hidden_states = hidden_states
|
||||
elif attn.norm_cross:
|
||||
encoder_hidden_states = attn.norm_encoder_hidden_states(encoder_hidden_states)
|
||||
|
||||
key = attn.to_k(encoder_hidden_states)
|
||||
value = attn.to_v(encoder_hidden_states)
|
||||
|
||||
query = attn.head_to_batch_dim(query)
|
||||
key = attn.head_to_batch_dim(key)
|
||||
value = attn.head_to_batch_dim(value)
|
||||
|
||||
attention_probs = attn.get_attention_scores(query, key, attention_mask)
|
||||
hidden_states = torch.bmm(attention_probs, value)
|
||||
hidden_states = attn.batch_to_head_dim(hidden_states)
|
||||
|
||||
# linear proj
|
||||
hidden_states = attn.to_out[0](hidden_states)
|
||||
# dropout
|
||||
hidden_states = attn.to_out[1](hidden_states)
|
||||
|
||||
if input_ndim == 4:
|
||||
hidden_states = hidden_states.transpose(-1, -2).reshape(batch_size, channel, height, width)
|
||||
|
||||
if attn.residual_connection:
|
||||
hidden_states = hidden_states + residual
|
||||
|
||||
hidden_states = hidden_states / attn.rescale_output_factor
|
||||
|
||||
return hidden_states
|
||||
|
||||
|
||||
class IPAttnProcessor(nn.Module):
|
||||
r"""
|
||||
Attention processor for IP-Adapater.
|
||||
Args:
|
||||
hidden_size (`int`):
|
||||
The hidden size of the attention layer.
|
||||
cross_attention_dim (`int`):
|
||||
The number of channels in the `encoder_hidden_states`.
|
||||
scale (`float`, defaults to 1.0):
|
||||
the weight scale of image prompt.
|
||||
num_tokens (`int`, defaults to 4 when do ip_adapter_plus it should be 16):
|
||||
The context length of the image features.
|
||||
"""
|
||||
|
||||
def __init__(self, hidden_size, cross_attention_dim=None, scale=1.0, num_tokens=4, skip=False,save_in_unet='down', atten_control=None):
|
||||
super().__init__()
|
||||
|
||||
self.hidden_size = hidden_size
|
||||
self.cross_attention_dim = cross_attention_dim
|
||||
self.scale = scale
|
||||
self.num_tokens = num_tokens
|
||||
self.skip = skip
|
||||
|
||||
self.atten_control = atten_control
|
||||
self.save_in_unet = save_in_unet
|
||||
|
||||
self.to_k_ip = nn.Linear(cross_attention_dim or hidden_size, hidden_size, bias=False)
|
||||
self.to_v_ip = nn.Linear(cross_attention_dim or hidden_size, hidden_size, bias=False)
|
||||
|
||||
def __call__(
|
||||
self,
|
||||
attn,
|
||||
hidden_states,
|
||||
encoder_hidden_states=None,
|
||||
attention_mask=None,
|
||||
temb=None,
|
||||
):
|
||||
residual = hidden_states
|
||||
|
||||
if attn.spatial_norm is not None:
|
||||
hidden_states = attn.spatial_norm(hidden_states, temb)
|
||||
|
||||
input_ndim = hidden_states.ndim
|
||||
|
||||
if input_ndim == 4:
|
||||
batch_size, channel, height, width = hidden_states.shape
|
||||
hidden_states = hidden_states.view(batch_size, channel, height * width).transpose(1, 2)
|
||||
|
||||
batch_size, sequence_length, _ = (
|
||||
hidden_states.shape if encoder_hidden_states is None else encoder_hidden_states.shape
|
||||
)
|
||||
attention_mask = attn.prepare_attention_mask(attention_mask, sequence_length, batch_size)
|
||||
|
||||
if attn.group_norm is not None:
|
||||
hidden_states = attn.group_norm(hidden_states.transpose(1, 2)).transpose(1, 2)
|
||||
|
||||
query = attn.to_q(hidden_states)
|
||||
|
||||
if encoder_hidden_states is None:
|
||||
encoder_hidden_states = hidden_states
|
||||
else:
|
||||
# get encoder_hidden_states, ip_hidden_states
|
||||
end_pos = encoder_hidden_states.shape[1] - self.num_tokens
|
||||
encoder_hidden_states, ip_hidden_states = (
|
||||
encoder_hidden_states[:, :end_pos, :],
|
||||
encoder_hidden_states[:, end_pos:, :],
|
||||
)
|
||||
if attn.norm_cross:
|
||||
encoder_hidden_states = attn.norm_encoder_hidden_states(encoder_hidden_states)
|
||||
|
||||
key = attn.to_k(encoder_hidden_states)
|
||||
value = attn.to_v(encoder_hidden_states)
|
||||
|
||||
query = attn.head_to_batch_dim(query)
|
||||
key = attn.head_to_batch_dim(key)
|
||||
value = attn.head_to_batch_dim(value)
|
||||
|
||||
attention_probs = attn.get_attention_scores(query, key, attention_mask)
|
||||
hidden_states = torch.bmm(attention_probs, value)
|
||||
hidden_states = attn.batch_to_head_dim(hidden_states)
|
||||
|
||||
if not self.skip:
|
||||
# for ip-adapter
|
||||
ip_key = self.to_k_ip(ip_hidden_states)
|
||||
ip_value = self.to_v_ip(ip_hidden_states)
|
||||
|
||||
ip_key = attn.head_to_batch_dim(ip_key)
|
||||
ip_value = attn.head_to_batch_dim(ip_value)
|
||||
|
||||
ip_attention_probs = attn.get_attention_scores(query, ip_key, None)
|
||||
self.attn_map = ip_attention_probs
|
||||
ip_hidden_states = torch.bmm(ip_attention_probs, ip_value)
|
||||
ip_hidden_states = attn.batch_to_head_dim(ip_hidden_states)
|
||||
|
||||
hidden_states = hidden_states + self.scale * ip_hidden_states
|
||||
|
||||
# linear proj
|
||||
hidden_states = attn.to_out[0](hidden_states)
|
||||
# dropout
|
||||
hidden_states = attn.to_out[1](hidden_states)
|
||||
|
||||
if input_ndim == 4:
|
||||
hidden_states = hidden_states.transpose(-1, -2).reshape(batch_size, channel, height, width)
|
||||
|
||||
if attn.residual_connection:
|
||||
hidden_states = hidden_states + residual
|
||||
|
||||
hidden_states = hidden_states / attn.rescale_output_factor
|
||||
|
||||
return hidden_states
|
||||
|
||||
|
||||
class AttnProcessor2_0(torch.nn.Module):
|
||||
r"""
|
||||
Processor for implementing scaled dot-product attention (enabled by default if you're using PyTorch 2.0).
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
hidden_size=None,
|
||||
cross_attention_dim=None,
|
||||
save_in_unet='down',
|
||||
atten_control=None,
|
||||
):
|
||||
super().__init__()
|
||||
if not hasattr(F, "scaled_dot_product_attention"):
|
||||
raise ImportError("AttnProcessor2_0 requires PyTorch 2.0, to use it, please upgrade PyTorch to 2.0.")
|
||||
self.atten_control = atten_control
|
||||
self.save_in_unet = save_in_unet
|
||||
|
||||
def __call__(
|
||||
self,
|
||||
attn,
|
||||
hidden_states,
|
||||
encoder_hidden_states=None,
|
||||
attention_mask=None,
|
||||
temb=None,
|
||||
):
|
||||
residual = hidden_states
|
||||
|
||||
if attn.spatial_norm is not None:
|
||||
hidden_states = attn.spatial_norm(hidden_states, temb)
|
||||
|
||||
input_ndim = hidden_states.ndim
|
||||
|
||||
if input_ndim == 4:
|
||||
batch_size, channel, height, width = hidden_states.shape
|
||||
hidden_states = hidden_states.view(batch_size, channel, height * width).transpose(1, 2)
|
||||
|
||||
batch_size, sequence_length, _ = (
|
||||
hidden_states.shape if encoder_hidden_states is None else encoder_hidden_states.shape
|
||||
)
|
||||
|
||||
if attention_mask is not None:
|
||||
attention_mask = attn.prepare_attention_mask(attention_mask, sequence_length, batch_size)
|
||||
# scaled_dot_product_attention expects attention_mask shape to be
|
||||
# (batch, heads, source_length, target_length)
|
||||
attention_mask = attention_mask.view(batch_size, attn.heads, -1, attention_mask.shape[-1])
|
||||
|
||||
if attn.group_norm is not None:
|
||||
hidden_states = attn.group_norm(hidden_states.transpose(1, 2)).transpose(1, 2)
|
||||
|
||||
query = attn.to_q(hidden_states)
|
||||
|
||||
if encoder_hidden_states is None:
|
||||
encoder_hidden_states = hidden_states
|
||||
elif attn.norm_cross:
|
||||
encoder_hidden_states = attn.norm_encoder_hidden_states(encoder_hidden_states)
|
||||
|
||||
key = attn.to_k(encoder_hidden_states)
|
||||
value = attn.to_v(encoder_hidden_states)
|
||||
|
||||
inner_dim = key.shape[-1]
|
||||
head_dim = inner_dim // attn.heads
|
||||
|
||||
query = query.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
key = key.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
value = value.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
# the output of sdp = (batch, num_heads, seq_len, head_dim)
|
||||
# TODO: add support for attn.scale when we move to Torch 2.1
|
||||
hidden_states = F.scaled_dot_product_attention(
|
||||
query, key, value, attn_mask=attention_mask, dropout_p=0.0, is_causal=False
|
||||
)
|
||||
|
||||
hidden_states = hidden_states.transpose(1, 2).reshape(batch_size, -1, attn.heads * head_dim)
|
||||
hidden_states = hidden_states.to(query.dtype)
|
||||
|
||||
# linear proj
|
||||
hidden_states = attn.to_out[0](hidden_states)
|
||||
# dropout
|
||||
hidden_states = attn.to_out[1](hidden_states)
|
||||
|
||||
if input_ndim == 4:
|
||||
hidden_states = hidden_states.transpose(-1, -2).reshape(batch_size, channel, height, width)
|
||||
|
||||
if attn.residual_connection:
|
||||
hidden_states = hidden_states + residual
|
||||
|
||||
hidden_states = hidden_states / attn.rescale_output_factor
|
||||
|
||||
return hidden_states
|
||||
|
||||
|
||||
class IPAttnProcessor2_0(torch.nn.Module):
|
||||
r"""
|
||||
Attention processor for IP-Adapater for PyTorch 2.0.
|
||||
Args:
|
||||
hidden_size (`int`):
|
||||
The hidden size of the attention layer.
|
||||
cross_attention_dim (`int`):
|
||||
The number of channels in the `encoder_hidden_states`.
|
||||
scale (`float`, defaults to 1.0):
|
||||
the weight scale of image prompt.
|
||||
num_tokens (`int`, defaults to 4 when do ip_adapter_plus it should be 16):
|
||||
The context length of the image features.
|
||||
"""
|
||||
|
||||
def __init__(self, hidden_size, cross_attention_dim=None, scale=1.0, num_tokens=4, skip=False,save_in_unet='down', atten_control=None):
|
||||
super().__init__()
|
||||
|
||||
if not hasattr(F, "scaled_dot_product_attention"):
|
||||
raise ImportError("AttnProcessor2_0 requires PyTorch 2.0, to use it, please upgrade PyTorch to 2.0.")
|
||||
|
||||
self.hidden_size = hidden_size
|
||||
self.cross_attention_dim = cross_attention_dim
|
||||
self.scale = scale
|
||||
self.num_tokens = num_tokens
|
||||
self.skip = skip
|
||||
|
||||
self.atten_control = atten_control
|
||||
self.save_in_unet = save_in_unet
|
||||
|
||||
self.to_k_ip = nn.Linear(cross_attention_dim or hidden_size, hidden_size, bias=False)
|
||||
self.to_v_ip = nn.Linear(cross_attention_dim or hidden_size, hidden_size, bias=False)
|
||||
|
||||
def __call__(
|
||||
self,
|
||||
attn,
|
||||
hidden_states,
|
||||
encoder_hidden_states=None,
|
||||
attention_mask=None,
|
||||
temb=None,
|
||||
):
|
||||
residual = hidden_states
|
||||
|
||||
if attn.spatial_norm is not None:
|
||||
hidden_states = attn.spatial_norm(hidden_states, temb)
|
||||
|
||||
input_ndim = hidden_states.ndim
|
||||
|
||||
if input_ndim == 4:
|
||||
batch_size, channel, height, width = hidden_states.shape
|
||||
hidden_states = hidden_states.view(batch_size, channel, height * width).transpose(1, 2)
|
||||
|
||||
batch_size, sequence_length, _ = (
|
||||
hidden_states.shape if encoder_hidden_states is None else encoder_hidden_states.shape
|
||||
)
|
||||
|
||||
if attention_mask is not None:
|
||||
attention_mask = attn.prepare_attention_mask(attention_mask, sequence_length, batch_size)
|
||||
# scaled_dot_product_attention expects attention_mask shape to be
|
||||
# (batch, heads, source_length, target_length)
|
||||
attention_mask = attention_mask.view(batch_size, attn.heads, -1, attention_mask.shape[-1])
|
||||
|
||||
if attn.group_norm is not None:
|
||||
hidden_states = attn.group_norm(hidden_states.transpose(1, 2)).transpose(1, 2)
|
||||
|
||||
query = attn.to_q(hidden_states)
|
||||
|
||||
if encoder_hidden_states is None:
|
||||
encoder_hidden_states = hidden_states
|
||||
else:
|
||||
# get encoder_hidden_states, ip_hidden_states
|
||||
end_pos = encoder_hidden_states.shape[1] - self.num_tokens
|
||||
encoder_hidden_states, ip_hidden_states = (
|
||||
encoder_hidden_states[:, :end_pos, :],
|
||||
encoder_hidden_states[:, end_pos:, :],
|
||||
)
|
||||
if attn.norm_cross:
|
||||
encoder_hidden_states = attn.norm_encoder_hidden_states(encoder_hidden_states)
|
||||
|
||||
key = attn.to_k(encoder_hidden_states)
|
||||
value = attn.to_v(encoder_hidden_states)
|
||||
|
||||
inner_dim = key.shape[-1]
|
||||
head_dim = inner_dim // attn.heads
|
||||
|
||||
query = query.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
key = key.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
value = value.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
# the output of sdp = (batch, num_heads, seq_len, head_dim)
|
||||
# TODO: add support for attn.scale when we move to Torch 2.1
|
||||
hidden_states = F.scaled_dot_product_attention(
|
||||
query, key, value, attn_mask=attention_mask, dropout_p=0.0, is_causal=False
|
||||
)
|
||||
|
||||
hidden_states = hidden_states.transpose(1, 2).reshape(batch_size, -1, attn.heads * head_dim)
|
||||
hidden_states = hidden_states.to(query.dtype)
|
||||
|
||||
if not self.skip:
|
||||
# for ip-adapter
|
||||
ip_key = self.to_k_ip(ip_hidden_states)
|
||||
ip_value = self.to_v_ip(ip_hidden_states)
|
||||
|
||||
ip_key = ip_key.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
ip_value = ip_value.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
# the output of sdp = (batch, num_heads, seq_len, head_dim)
|
||||
# TODO: add support for attn.scale when we move to Torch 2.1
|
||||
ip_hidden_states = F.scaled_dot_product_attention(
|
||||
query, ip_key, ip_value, attn_mask=None, dropout_p=0.0, is_causal=False
|
||||
)
|
||||
with torch.no_grad():
|
||||
self.attn_map = query @ ip_key.transpose(-2, -1).softmax(dim=-1)
|
||||
#print(self.attn_map.shape)
|
||||
|
||||
ip_hidden_states = ip_hidden_states.transpose(1, 2).reshape(batch_size, -1, attn.heads * head_dim)
|
||||
ip_hidden_states = ip_hidden_states.to(query.dtype)
|
||||
|
||||
hidden_states = hidden_states + self.scale * ip_hidden_states
|
||||
|
||||
# linear proj
|
||||
hidden_states = attn.to_out[0](hidden_states)
|
||||
# dropout
|
||||
hidden_states = attn.to_out[1](hidden_states)
|
||||
|
||||
if input_ndim == 4:
|
||||
hidden_states = hidden_states.transpose(-1, -2).reshape(batch_size, channel, height, width)
|
||||
|
||||
if attn.residual_connection:
|
||||
hidden_states = hidden_states + residual
|
||||
|
||||
hidden_states = hidden_states / attn.rescale_output_factor
|
||||
|
||||
return hidden_states
|
||||
|
||||
|
||||
class IP_CS_AttnProcessor2_0(torch.nn.Module):
|
||||
r"""
|
||||
Attention processor for IP-Adapater for PyTorch 2.0.
|
||||
Args:
|
||||
hidden_size (`int`):
|
||||
The hidden size of the attention layer.
|
||||
cross_attention_dim (`int`):
|
||||
The number of channels in the `encoder_hidden_states`.
|
||||
scale (`float`, defaults to 1.0):
|
||||
the weight scale of image prompt.
|
||||
num_tokens (`int`, defaults to 4 when do ip_adapter_plus it should be 16):
|
||||
The context length of the image features.
|
||||
"""
|
||||
|
||||
def __init__(self, hidden_size, cross_attention_dim=None, content_scale=1.0,style_scale=1.0, num_content_tokens=4,num_style_tokens=4,
|
||||
skip=False,content=False, style=False):
|
||||
super().__init__()
|
||||
|
||||
if not hasattr(F, "scaled_dot_product_attention"):
|
||||
raise ImportError("AttnProcessor2_0 requires PyTorch 2.0, to use it, please upgrade PyTorch to 2.0.")
|
||||
|
||||
self.hidden_size = hidden_size
|
||||
self.cross_attention_dim = cross_attention_dim
|
||||
self.content_scale = content_scale
|
||||
self.style_scale = style_scale
|
||||
self.num_content_tokens = num_content_tokens
|
||||
self.num_style_tokens = num_style_tokens
|
||||
self.skip = skip
|
||||
|
||||
self.content = content
|
||||
self.style = style
|
||||
|
||||
if self.content or self.style:
|
||||
self.to_k_ip = nn.Linear(cross_attention_dim or hidden_size, hidden_size, bias=False)
|
||||
self.to_v_ip = nn.Linear(cross_attention_dim or hidden_size, hidden_size, bias=False)
|
||||
self.to_k_ip_content =None
|
||||
self.to_v_ip_content =None
|
||||
|
||||
def set_content_ipa(self,content_scale=1.0):
|
||||
|
||||
self.to_k_ip_content = nn.Linear(self.cross_attention_dim or self.hidden_size, self.hidden_size, bias=False)
|
||||
self.to_v_ip_content = nn.Linear(self.cross_attention_dim or self.hidden_size, self.hidden_size, bias=False)
|
||||
self.content_scale=content_scale
|
||||
self.content =True
|
||||
|
||||
def __call__(
|
||||
self,
|
||||
attn,
|
||||
hidden_states,
|
||||
encoder_hidden_states=None,
|
||||
attention_mask=None,
|
||||
temb=None,
|
||||
):
|
||||
residual = hidden_states
|
||||
|
||||
if attn.spatial_norm is not None:
|
||||
hidden_states = attn.spatial_norm(hidden_states, temb)
|
||||
|
||||
input_ndim = hidden_states.ndim
|
||||
|
||||
if input_ndim == 4:
|
||||
batch_size, channel, height, width = hidden_states.shape
|
||||
hidden_states = hidden_states.view(batch_size, channel, height * width).transpose(1, 2)
|
||||
|
||||
batch_size, sequence_length, _ = (
|
||||
hidden_states.shape if encoder_hidden_states is None else encoder_hidden_states.shape
|
||||
)
|
||||
|
||||
if attention_mask is not None:
|
||||
attention_mask = attn.prepare_attention_mask(attention_mask, sequence_length, batch_size)
|
||||
# scaled_dot_product_attention expects attention_mask shape to be
|
||||
# (batch, heads, source_length, target_length)
|
||||
attention_mask = attention_mask.view(batch_size, attn.heads, -1, attention_mask.shape[-1])
|
||||
|
||||
if attn.group_norm is not None:
|
||||
hidden_states = attn.group_norm(hidden_states.transpose(1, 2)).transpose(1, 2)
|
||||
|
||||
query = attn.to_q(hidden_states)
|
||||
|
||||
if encoder_hidden_states is None:
|
||||
encoder_hidden_states = hidden_states
|
||||
else:
|
||||
# get encoder_hidden_states, ip_hidden_states
|
||||
end_pos = encoder_hidden_states.shape[1] - self.num_content_tokens-self.num_style_tokens
|
||||
encoder_hidden_states, ip_content_hidden_states,ip_style_hidden_states = (
|
||||
encoder_hidden_states[:, :end_pos, :],
|
||||
encoder_hidden_states[:, end_pos:end_pos + self.num_content_tokens, :],
|
||||
encoder_hidden_states[:, end_pos + self.num_content_tokens:, :],
|
||||
)
|
||||
if attn.norm_cross:
|
||||
encoder_hidden_states = attn.norm_encoder_hidden_states(encoder_hidden_states)
|
||||
|
||||
key = attn.to_k(encoder_hidden_states)
|
||||
value = attn.to_v(encoder_hidden_states)
|
||||
|
||||
inner_dim = key.shape[-1]
|
||||
head_dim = inner_dim // attn.heads
|
||||
|
||||
query = query.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
key = key.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
value = value.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
# the output of sdp = (batch, num_heads, seq_len, head_dim)
|
||||
# TODO: add support for attn.scale when we move to Torch 2.1
|
||||
hidden_states = F.scaled_dot_product_attention(
|
||||
query, key, value, attn_mask=attention_mask, dropout_p=0.0, is_causal=False
|
||||
)
|
||||
|
||||
hidden_states = hidden_states.transpose(1, 2).reshape(batch_size, -1, attn.heads * head_dim)
|
||||
hidden_states = hidden_states.to(query.dtype)
|
||||
|
||||
if not self.skip and self.content is True:
|
||||
# print('content#####################################################')
|
||||
# for ip-content-adapter
|
||||
if self.to_k_ip_content is None:
|
||||
|
||||
ip_content_key = self.to_k_ip(ip_content_hidden_states)
|
||||
ip_content_value = self.to_v_ip(ip_content_hidden_states)
|
||||
else:
|
||||
ip_content_key = self.to_k_ip_content(ip_content_hidden_states)
|
||||
ip_content_value = self.to_v_ip_content(ip_content_hidden_states)
|
||||
|
||||
ip_content_key = ip_content_key.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
ip_content_value = ip_content_value.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
# the output of sdp = (batch, num_heads, seq_len, head_dim)
|
||||
# TODO: add support for attn.scale when we move to Torch 2.1
|
||||
ip_content_hidden_states = F.scaled_dot_product_attention(
|
||||
query, ip_content_key, ip_content_value, attn_mask=None, dropout_p=0.0, is_causal=False
|
||||
)
|
||||
|
||||
|
||||
ip_content_hidden_states = ip_content_hidden_states.transpose(1, 2).reshape(batch_size, -1, attn.heads * head_dim)
|
||||
ip_content_hidden_states = ip_content_hidden_states.to(query.dtype)
|
||||
|
||||
|
||||
hidden_states = hidden_states + self.content_scale * ip_content_hidden_states
|
||||
|
||||
if not self.skip and self.style is True:
|
||||
# for ip-style-adapter
|
||||
ip_style_key = self.to_k_ip(ip_style_hidden_states)
|
||||
ip_style_value = self.to_v_ip(ip_style_hidden_states)
|
||||
|
||||
ip_style_key = ip_style_key.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
ip_style_value = ip_style_value.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
# the output of sdp = (batch, num_heads, seq_len, head_dim)
|
||||
# TODO: add support for attn.scale when we move to Torch 2.1
|
||||
ip_style_hidden_states = F.scaled_dot_product_attention(
|
||||
query, ip_style_key, ip_style_value, attn_mask=None, dropout_p=0.0, is_causal=False
|
||||
)
|
||||
|
||||
ip_style_hidden_states = ip_style_hidden_states.transpose(1, 2).reshape(batch_size, -1,
|
||||
attn.heads * head_dim)
|
||||
ip_style_hidden_states = ip_style_hidden_states.to(query.dtype)
|
||||
|
||||
hidden_states = hidden_states + self.style_scale * ip_style_hidden_states
|
||||
|
||||
# linear proj
|
||||
hidden_states = attn.to_out[0](hidden_states)
|
||||
# dropout
|
||||
hidden_states = attn.to_out[1](hidden_states)
|
||||
|
||||
if input_ndim == 4:
|
||||
hidden_states = hidden_states.transpose(-1, -2).reshape(batch_size, channel, height, width)
|
||||
|
||||
if attn.residual_connection:
|
||||
hidden_states = hidden_states + residual
|
||||
|
||||
hidden_states = hidden_states / attn.rescale_output_factor
|
||||
|
||||
return hidden_states
|
||||
|
||||
## for controlnet
|
||||
class CNAttnProcessor:
|
||||
r"""
|
||||
Default processor for performing attention-related computations.
|
||||
"""
|
||||
|
||||
def __init__(self, num_tokens=4,save_in_unet='down',atten_control=None):
|
||||
self.num_tokens = num_tokens
|
||||
self.atten_control = atten_control
|
||||
self.save_in_unet = save_in_unet
|
||||
|
||||
def __call__(self, attn, hidden_states, encoder_hidden_states=None, attention_mask=None, temb=None):
|
||||
residual = hidden_states
|
||||
|
||||
if attn.spatial_norm is not None:
|
||||
hidden_states = attn.spatial_norm(hidden_states, temb)
|
||||
|
||||
input_ndim = hidden_states.ndim
|
||||
|
||||
if input_ndim == 4:
|
||||
batch_size, channel, height, width = hidden_states.shape
|
||||
hidden_states = hidden_states.view(batch_size, channel, height * width).transpose(1, 2)
|
||||
|
||||
batch_size, sequence_length, _ = (
|
||||
hidden_states.shape if encoder_hidden_states is None else encoder_hidden_states.shape
|
||||
)
|
||||
attention_mask = attn.prepare_attention_mask(attention_mask, sequence_length, batch_size)
|
||||
|
||||
if attn.group_norm is not None:
|
||||
hidden_states = attn.group_norm(hidden_states.transpose(1, 2)).transpose(1, 2)
|
||||
|
||||
query = attn.to_q(hidden_states)
|
||||
|
||||
if encoder_hidden_states is None:
|
||||
encoder_hidden_states = hidden_states
|
||||
else:
|
||||
end_pos = encoder_hidden_states.shape[1] - self.num_tokens
|
||||
encoder_hidden_states = encoder_hidden_states[:, :end_pos] # only use text
|
||||
if attn.norm_cross:
|
||||
encoder_hidden_states = attn.norm_encoder_hidden_states(encoder_hidden_states)
|
||||
|
||||
key = attn.to_k(encoder_hidden_states)
|
||||
value = attn.to_v(encoder_hidden_states)
|
||||
|
||||
query = attn.head_to_batch_dim(query)
|
||||
key = attn.head_to_batch_dim(key)
|
||||
value = attn.head_to_batch_dim(value)
|
||||
|
||||
attention_probs = attn.get_attention_scores(query, key, attention_mask)
|
||||
hidden_states = torch.bmm(attention_probs, value)
|
||||
hidden_states = attn.batch_to_head_dim(hidden_states)
|
||||
|
||||
# linear proj
|
||||
hidden_states = attn.to_out[0](hidden_states)
|
||||
# dropout
|
||||
hidden_states = attn.to_out[1](hidden_states)
|
||||
|
||||
if input_ndim == 4:
|
||||
hidden_states = hidden_states.transpose(-1, -2).reshape(batch_size, channel, height, width)
|
||||
|
||||
if attn.residual_connection:
|
||||
hidden_states = hidden_states + residual
|
||||
|
||||
hidden_states = hidden_states / attn.rescale_output_factor
|
||||
|
||||
return hidden_states
|
||||
|
||||
|
||||
class CNAttnProcessor2_0:
|
||||
r"""
|
||||
Processor for implementing scaled dot-product attention (enabled by default if you're using PyTorch 2.0).
|
||||
"""
|
||||
|
||||
def __init__(self, num_tokens=4, save_in_unet='down', atten_control=None):
|
||||
if not hasattr(F, "scaled_dot_product_attention"):
|
||||
raise ImportError("AttnProcessor2_0 requires PyTorch 2.0, to use it, please upgrade PyTorch to 2.0.")
|
||||
self.num_tokens = num_tokens
|
||||
self.atten_control = atten_control
|
||||
self.save_in_unet = save_in_unet
|
||||
|
||||
def __call__(
|
||||
self,
|
||||
attn,
|
||||
hidden_states,
|
||||
encoder_hidden_states=None,
|
||||
attention_mask=None,
|
||||
temb=None,
|
||||
):
|
||||
residual = hidden_states
|
||||
|
||||
if attn.spatial_norm is not None:
|
||||
hidden_states = attn.spatial_norm(hidden_states, temb)
|
||||
|
||||
input_ndim = hidden_states.ndim
|
||||
|
||||
if input_ndim == 4:
|
||||
batch_size, channel, height, width = hidden_states.shape
|
||||
hidden_states = hidden_states.view(batch_size, channel, height * width).transpose(1, 2)
|
||||
|
||||
batch_size, sequence_length, _ = (
|
||||
hidden_states.shape if encoder_hidden_states is None else encoder_hidden_states.shape
|
||||
)
|
||||
|
||||
if attention_mask is not None:
|
||||
attention_mask = attn.prepare_attention_mask(attention_mask, sequence_length, batch_size)
|
||||
# scaled_dot_product_attention expects attention_mask shape to be
|
||||
# (batch, heads, source_length, target_length)
|
||||
attention_mask = attention_mask.view(batch_size, attn.heads, -1, attention_mask.shape[-1])
|
||||
|
||||
if attn.group_norm is not None:
|
||||
hidden_states = attn.group_norm(hidden_states.transpose(1, 2)).transpose(1, 2)
|
||||
|
||||
query = attn.to_q(hidden_states)
|
||||
|
||||
if encoder_hidden_states is None:
|
||||
encoder_hidden_states = hidden_states
|
||||
else:
|
||||
end_pos = encoder_hidden_states.shape[1] - self.num_tokens
|
||||
encoder_hidden_states = encoder_hidden_states[:, :end_pos] # only use text
|
||||
if attn.norm_cross:
|
||||
encoder_hidden_states = attn.norm_encoder_hidden_states(encoder_hidden_states)
|
||||
|
||||
key = attn.to_k(encoder_hidden_states)
|
||||
value = attn.to_v(encoder_hidden_states)
|
||||
|
||||
inner_dim = key.shape[-1]
|
||||
head_dim = inner_dim // attn.heads
|
||||
|
||||
query = query.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
key = key.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
value = value.view(batch_size, -1, attn.heads, head_dim).transpose(1, 2)
|
||||
|
||||
# the output of sdp = (batch, num_heads, seq_len, head_dim)
|
||||
# TODO: add support for attn.scale when we move to Torch 2.1
|
||||
hidden_states = F.scaled_dot_product_attention(
|
||||
query, key, value, attn_mask=attention_mask, dropout_p=0.0, is_causal=False
|
||||
)
|
||||
|
||||
hidden_states = hidden_states.transpose(1, 2).reshape(batch_size, -1, attn.heads * head_dim)
|
||||
hidden_states = hidden_states.to(query.dtype)
|
||||
|
||||
# linear proj
|
||||
hidden_states = attn.to_out[0](hidden_states)
|
||||
# dropout
|
||||
hidden_states = attn.to_out[1](hidden_states)
|
||||
|
||||
if input_ndim == 4:
|
||||
hidden_states = hidden_states.transpose(-1, -2).reshape(batch_size, channel, height, width)
|
||||
|
||||
if attn.residual_connection:
|
||||
hidden_states = hidden_states + residual
|
||||
|
||||
hidden_states = hidden_states / attn.rescale_output_factor
|
||||
|
||||
return hidden_states
|
||||
@@ -0,0 +1,158 @@
|
||||
# modified from https://github.com/mlfoundations/open_flamingo/blob/main/open_flamingo/src/helpers.py
|
||||
# and https://github.com/lucidrains/imagen-pytorch/blob/main/imagen_pytorch/imagen_pytorch.py
|
||||
|
||||
import math
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from einops import rearrange
|
||||
from einops.layers.torch import Rearrange
|
||||
|
||||
|
||||
# FFN
|
||||
def FeedForward(dim, mult=4):
|
||||
inner_dim = int(dim * mult)
|
||||
return nn.Sequential(
|
||||
nn.LayerNorm(dim),
|
||||
nn.Linear(dim, inner_dim, bias=False),
|
||||
nn.GELU(),
|
||||
nn.Linear(inner_dim, dim, bias=False),
|
||||
)
|
||||
|
||||
|
||||
def reshape_tensor(x, heads):
|
||||
bs, length, width = x.shape
|
||||
# (bs, length, width) --> (bs, length, n_heads, dim_per_head)
|
||||
x = x.view(bs, length, heads, -1)
|
||||
# (bs, length, n_heads, dim_per_head) --> (bs, n_heads, length, dim_per_head)
|
||||
x = x.transpose(1, 2)
|
||||
# (bs, n_heads, length, dim_per_head) --> (bs*n_heads, length, dim_per_head)
|
||||
x = x.reshape(bs, heads, length, -1)
|
||||
return x
|
||||
|
||||
|
||||
class PerceiverAttention(nn.Module):
|
||||
def __init__(self, *, dim, dim_head=64, heads=8):
|
||||
super().__init__()
|
||||
self.scale = dim_head**-0.5
|
||||
self.dim_head = dim_head
|
||||
self.heads = heads
|
||||
inner_dim = dim_head * heads
|
||||
|
||||
self.norm1 = nn.LayerNorm(dim)
|
||||
self.norm2 = nn.LayerNorm(dim)
|
||||
|
||||
self.to_q = nn.Linear(dim, inner_dim, bias=False)
|
||||
self.to_kv = nn.Linear(dim, inner_dim * 2, bias=False)
|
||||
self.to_out = nn.Linear(inner_dim, dim, bias=False)
|
||||
|
||||
def forward(self, x, latents):
|
||||
"""
|
||||
Args:
|
||||
x (torch.Tensor): image features
|
||||
shape (b, n1, D)
|
||||
latent (torch.Tensor): latent features
|
||||
shape (b, n2, D)
|
||||
"""
|
||||
x = self.norm1(x)
|
||||
latents = self.norm2(latents)
|
||||
|
||||
b, l, _ = latents.shape
|
||||
|
||||
q = self.to_q(latents)
|
||||
kv_input = torch.cat((x, latents), dim=-2)
|
||||
k, v = self.to_kv(kv_input).chunk(2, dim=-1)
|
||||
|
||||
q = reshape_tensor(q, self.heads)
|
||||
k = reshape_tensor(k, self.heads)
|
||||
v = reshape_tensor(v, self.heads)
|
||||
|
||||
# attention
|
||||
scale = 1 / math.sqrt(math.sqrt(self.dim_head))
|
||||
weight = (q * scale) @ (k * scale).transpose(-2, -1) # More stable with f16 than dividing afterwards
|
||||
weight = torch.softmax(weight.float(), dim=-1).type(weight.dtype)
|
||||
out = weight @ v
|
||||
|
||||
out = out.permute(0, 2, 1, 3).reshape(b, l, -1)
|
||||
|
||||
return self.to_out(out)
|
||||
|
||||
|
||||
class Resampler(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
dim=1024,
|
||||
depth=8,
|
||||
dim_head=64,
|
||||
heads=16,
|
||||
num_queries=8,
|
||||
embedding_dim=768,
|
||||
output_dim=1024,
|
||||
ff_mult=4,
|
||||
max_seq_len: int = 257, # CLIP tokens + CLS token
|
||||
apply_pos_emb: bool = False,
|
||||
num_latents_mean_pooled: int = 0, # number of latents derived from mean pooled representation of the sequence
|
||||
):
|
||||
super().__init__()
|
||||
self.pos_emb = nn.Embedding(max_seq_len, embedding_dim) if apply_pos_emb else None
|
||||
|
||||
self.latents = nn.Parameter(torch.randn(1, num_queries, dim) / dim**0.5)
|
||||
|
||||
self.proj_in = nn.Linear(embedding_dim, dim)
|
||||
|
||||
self.proj_out = nn.Linear(dim, output_dim)
|
||||
self.norm_out = nn.LayerNorm(output_dim)
|
||||
|
||||
self.to_latents_from_mean_pooled_seq = (
|
||||
nn.Sequential(
|
||||
nn.LayerNorm(dim),
|
||||
nn.Linear(dim, dim * num_latents_mean_pooled),
|
||||
Rearrange("b (n d) -> b n d", n=num_latents_mean_pooled),
|
||||
)
|
||||
if num_latents_mean_pooled > 0
|
||||
else None
|
||||
)
|
||||
|
||||
self.layers = nn.ModuleList([])
|
||||
for _ in range(depth):
|
||||
self.layers.append(
|
||||
nn.ModuleList(
|
||||
[
|
||||
PerceiverAttention(dim=dim, dim_head=dim_head, heads=heads),
|
||||
FeedForward(dim=dim, mult=ff_mult),
|
||||
]
|
||||
)
|
||||
)
|
||||
|
||||
def forward(self, x):
|
||||
if self.pos_emb is not None:
|
||||
n, device = x.shape[1], x.device
|
||||
pos_emb = self.pos_emb(torch.arange(n, device=device))
|
||||
x = x + pos_emb
|
||||
|
||||
latents = self.latents.repeat(x.size(0), 1, 1)
|
||||
|
||||
x = self.proj_in(x)
|
||||
|
||||
if self.to_latents_from_mean_pooled_seq:
|
||||
meanpooled_seq = masked_mean(x, dim=1, mask=torch.ones(x.shape[:2], device=x.device, dtype=torch.bool))
|
||||
meanpooled_latents = self.to_latents_from_mean_pooled_seq(meanpooled_seq)
|
||||
latents = torch.cat((meanpooled_latents, latents), dim=-2)
|
||||
|
||||
for attn, ff in self.layers:
|
||||
latents = attn(x, latents) + latents
|
||||
latents = ff(latents) + latents
|
||||
|
||||
latents = self.proj_out(latents)
|
||||
return self.norm_out(latents)
|
||||
|
||||
|
||||
def masked_mean(t, *, dim, mask=None):
|
||||
if mask is None:
|
||||
return t.mean(dim=dim)
|
||||
|
||||
denom = mask.sum(dim=dim, keepdim=True)
|
||||
mask = rearrange(mask, "b n -> b n 1")
|
||||
masked_t = t.masked_fill(~mask, 0.0)
|
||||
|
||||
return masked_t.sum(dim=dim) / denom.clamp(min=1e-5)
|
||||
@@ -0,0 +1,142 @@
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
BLOCKS = {
|
||||
'content': ['down_blocks'],
|
||||
'style': ["up_blocks"],
|
||||
|
||||
}
|
||||
|
||||
controlnet_BLOCKS = {
|
||||
'content': [],
|
||||
'style': ["down_blocks"],
|
||||
}
|
||||
|
||||
|
||||
def resize_width_height(width, height, min_short_side=512, max_long_side=1024):
|
||||
|
||||
if width < height:
|
||||
|
||||
if width < min_short_side:
|
||||
scale_factor = min_short_side / width
|
||||
new_width = min_short_side
|
||||
new_height = int(height * scale_factor)
|
||||
else:
|
||||
new_width, new_height = width, height
|
||||
else:
|
||||
|
||||
if height < min_short_side:
|
||||
scale_factor = min_short_side / height
|
||||
new_width = int(width * scale_factor)
|
||||
new_height = min_short_side
|
||||
else:
|
||||
new_width, new_height = width, height
|
||||
|
||||
if max(new_width, new_height) > max_long_side:
|
||||
scale_factor = max_long_side / max(new_width, new_height)
|
||||
new_width = int(new_width * scale_factor)
|
||||
new_height = int(new_height * scale_factor)
|
||||
return new_width, new_height
|
||||
|
||||
def resize_content(content_image):
|
||||
max_long_side = 1024
|
||||
min_short_side = 1024
|
||||
|
||||
new_width, new_height = resize_width_height(content_image.size[0], content_image.size[1],
|
||||
min_short_side=min_short_side, max_long_side=max_long_side)
|
||||
height = new_height // 16 * 16
|
||||
width = new_width // 16 * 16
|
||||
content_image = content_image.resize((width, height))
|
||||
|
||||
return width,height,content_image
|
||||
|
||||
attn_maps = {}
|
||||
def hook_fn(name):
|
||||
def forward_hook(module, input, output):
|
||||
if hasattr(module.processor, "attn_map"):
|
||||
attn_maps[name] = module.processor.attn_map
|
||||
del module.processor.attn_map
|
||||
|
||||
return forward_hook
|
||||
|
||||
def register_cross_attention_hook(unet):
|
||||
for name, module in unet.named_modules():
|
||||
if name.split('.')[-1].startswith('attn2'):
|
||||
module.register_forward_hook(hook_fn(name))
|
||||
|
||||
return unet
|
||||
|
||||
def upscale(attn_map, target_size):
|
||||
attn_map = torch.mean(attn_map, dim=0)
|
||||
attn_map = attn_map.permute(1,0)
|
||||
temp_size = None
|
||||
|
||||
for i in range(0,5):
|
||||
scale = 2 ** i
|
||||
if ( target_size[0] // scale ) * ( target_size[1] // scale) == attn_map.shape[1]*64:
|
||||
temp_size = (target_size[0]//(scale*8), target_size[1]//(scale*8))
|
||||
break
|
||||
|
||||
assert temp_size is not None, "temp_size cannot is None"
|
||||
|
||||
attn_map = attn_map.view(attn_map.shape[0], *temp_size)
|
||||
|
||||
attn_map = F.interpolate(
|
||||
attn_map.unsqueeze(0).to(dtype=torch.float32),
|
||||
size=target_size,
|
||||
mode='bilinear',
|
||||
align_corners=False
|
||||
)[0]
|
||||
|
||||
attn_map = torch.softmax(attn_map, dim=0)
|
||||
return attn_map
|
||||
def get_net_attn_map(image_size, batch_size=2, instance_or_negative=False, detach=True):
|
||||
|
||||
idx = 0 if instance_or_negative else 1
|
||||
net_attn_maps = []
|
||||
|
||||
for name, attn_map in attn_maps.items():
|
||||
attn_map = attn_map.cpu() if detach else attn_map
|
||||
attn_map = torch.chunk(attn_map, batch_size)[idx].squeeze()
|
||||
attn_map = upscale(attn_map, image_size)
|
||||
net_attn_maps.append(attn_map)
|
||||
|
||||
net_attn_maps = torch.mean(torch.stack(net_attn_maps,dim=0),dim=0)
|
||||
|
||||
return net_attn_maps
|
||||
|
||||
def attnmaps2images(net_attn_maps):
|
||||
|
||||
#total_attn_scores = 0
|
||||
images = []
|
||||
|
||||
for attn_map in net_attn_maps:
|
||||
attn_map = attn_map.cpu().numpy()
|
||||
#total_attn_scores += attn_map.mean().item()
|
||||
|
||||
normalized_attn_map = (attn_map - np.min(attn_map)) / (np.max(attn_map) - np.min(attn_map)) * 255
|
||||
normalized_attn_map = normalized_attn_map.astype(np.uint8)
|
||||
#print("norm: ", normalized_attn_map.shape)
|
||||
image = Image.fromarray(normalized_attn_map)
|
||||
|
||||
#image = fix_save_attn_map(attn_map)
|
||||
images.append(image)
|
||||
|
||||
#print(total_attn_scores)
|
||||
return images
|
||||
def is_torch2_available():
|
||||
return hasattr(F, "scaled_dot_product_attention")
|
||||
|
||||
def get_generator(seed, device):
|
||||
|
||||
if seed is not None:
|
||||
if isinstance(seed, list):
|
||||
generator = [torch.Generator(device).manual_seed(seed_item) for seed_item in seed]
|
||||
else:
|
||||
generator = torch.Generator(device).manual_seed(seed)
|
||||
else:
|
||||
generator = None
|
||||
|
||||
return generator
|
||||
@@ -0,0 +1,18 @@
|
||||
diffusers==0.25.1
|
||||
torch==2.0.1
|
||||
torchaudio==2.0.2
|
||||
torchvision==0.15.2
|
||||
transformers==4.40.2
|
||||
accelerate
|
||||
safetensors
|
||||
einops
|
||||
spaces==0.19.4
|
||||
omegaconf
|
||||
peft
|
||||
huggingface-hub==0.24.5
|
||||
opencv-python
|
||||
insightface
|
||||
gradio
|
||||
controlnet_aux
|
||||
gdown
|
||||
peft
|
||||