Clean up: Remove unnecessary files, keep only ComfyUI node essentials
 weiweiliang
@@ -1,2 +0,0 @@
|
||||
# SCM syntax highlighting & preventing 3-way merges
|
||||
pixi.lock merge=binary linguist-language=YAML linguist-generated=true
|
||||
@@ -1,31 +0,0 @@
|
||||
-----BEGIN CERTIFICATE-----
|
||||
MIIFazCCA1OgAwIBAgIRAIIQz7DSQONZRGPgu2OCiwAwDQYJKoZIhvcNAQELBQAw
|
||||
TzELMAkGA1UEBhMCVVMxKTAnBgNVBAoTIEludGVybmV0IFNlY3VyaXR5IFJlc2Vh
|
||||
cmNoIEdyb3VwMRUwEwYDVQQDEwxJU1JHIFJvb3QgWDEwHhcNMTUwNjA0MTEwNDM4
|
||||
WhcNMzUwNjA0MTEwNDM4WjBPMQswCQYDVQQGEwJVUzEpMCcGA1UEChMgSW50ZXJu
|
||||
ZXQgU2VjdXJpdHkgUmVzZWFyY2ggR3JvdXAxFTATBgNVBAMTDElTUkcgUm9vdCBY
|
||||
MTCCAiIwDQYJKoZIhvcNAQEBBQADggIPADCCAgoCggIBAK3oJHP0FDfzm54rVygc
|
||||
h77ct984kIxuPOZXoHj3dcKi/vVqbvYATyjb3miGbESTtrFj/RQSa78f0uoxmyF+
|
||||
0TM8ukj13Xnfs7j/EvEhmkvBioZxaUpmZmyPfjxwv60pIgbz5MDmgK7iS4+3mX6U
|
||||
A5/TR5d8mUgjU+g4rk8Kb4Mu0UlXjIB0ttov0DiNewNwIRt18jA8+o+u3dpjq+sW
|
||||
T8KOEUt+zwvo/7V3LvSye0rgTBIlDHCNAymg4VMk7BPZ7hm/ELNKjD+Jo2FR3qyH
|
||||
B5T0Y3HsLuJvW5iB4YlcNHlsdu87kGJ55tukmi8mxdAQ4Q7e2RCOFvu396j3x+UC
|
||||
B5iPNgiV5+I3lg02dZ77DnKxHZu8A/lJBdiB3QW0KtZB6awBdpUKD9jf1b0SHzUv
|
||||
KBds0pjBqAlkd25HN7rOrFleaJ1/ctaJxQZBKT5ZPt0m9STJEadao0xAH0ahmbWn
|
||||
OlFuhjuefXKnEgV4We0+UXgVCwOPjdAvBbI+e0ocS3MFEvzG6uBQE3xDk3SzynTn
|
||||
jh8BCNAw1FtxNrQHusEwMFxIt4I7mKZ9YIqioymCzLq9gwQbooMDQaHWBfEbwrbw
|
||||
qHyGO0aoSCqI3Haadr8faqU9GY/rOPNk3sgrDQoo//fb4hVC1CLQJ13hef4Y53CI
|
||||
rU7m2Ys6xt0nUW7/vGT1M0NPAgMBAAGjQjBAMA4GA1UdDwEB/wQEAwIBBjAPBgNV
|
||||
HRMBAf8EBTADAQH/MB0GA1UdDgQWBBR5tFnme7bl5AFzgAiIyBpY9umbbjANBgkq
|
||||
hkiG9w0BAQsFAAOCAgEAVR9YqbyyqFDQDLHYGmkgJykIrGF1XIpu+ILlaS/V9lZL
|
||||
ubhzEFnTIZd+50xx+7LSYK05qAvqFyFWhfFQDlnrzuBZ6brJFe+GnY+EgPbk6ZGQ
|
||||
3BebYhtF8GaV0nxvwuo77x/Py9auJ/GpsMiu/X1+mvoiBOv/2X/qkSsisRcOj/KK
|
||||
NFtY2PwByVS5uCbMiogziUwthDyC3+6WVwW6LLv3xLfHTjuCvjHIInNzktHCgKQ5
|
||||
ORAzI4JMPJ+GslWYHb4phowim57iaztXOoJwTdwJx4nLCgdNbOhdjsnvzqvHu7Ur
|
||||
TkXWStAmzOVyyghqpZXjFaH3pO3JLF+l+/+sKAIuvtd7u+Nxe5AW0wdeRlN8NwdC
|
||||
jNPElpzVmbUq4JUagEiuTDkHzsxHpFKVK7q4+63SM1N95R1NbdWhscdCb+ZAJzVc
|
||||
oyi3B43njTOQ5yOf+1CceWxG1bQVs5ZufpsMljq4Ui0/1lvh+wjChP4kqKOJ2qxq
|
||||
4RgqsahDYVvTH9w7jXbyLeiNdd8XM2w9U/t7y0Ff/9yi0GE44Za4rF2LN9d11TPA
|
||||
mRGunUHBcnWEvgJBQl9nJEiU0Zsnvgc/ubhPgXRR4Xq37Z0j4r7g1SgEEzwxA57d
|
||||
emyPxgcYxn/eR44/KJ4EBs+lVDR3veyJm+kXQ99b21/+jh5Xos1AnX5iItreGCc=
|
||||
-----END CERTIFICATE-----
|
||||
@@ -1,80 +0,0 @@
|
||||
# Code of Conduct
|
||||
|
||||
## Our Pledge
|
||||
|
||||
In the interest of fostering an open and welcoming environment, we as
|
||||
contributors and maintainers pledge to make participation in our project and
|
||||
our community a harassment-free experience for everyone, regardless of age, body
|
||||
size, disability, ethnicity, sex characteristics, gender identity and expression,
|
||||
level of experience, education, socio-economic status, nationality, personal
|
||||
appearance, race, religion, or sexual identity and orientation.
|
||||
|
||||
## Our Standards
|
||||
|
||||
Examples of behavior that contributes to creating a positive environment
|
||||
include:
|
||||
|
||||
* Using welcoming and inclusive language
|
||||
* Being respectful of differing viewpoints and experiences
|
||||
* Gracefully accepting constructive criticism
|
||||
* Focusing on what is best for the community
|
||||
* Showing empathy towards other community members
|
||||
|
||||
Examples of unacceptable behavior by participants include:
|
||||
|
||||
* The use of sexualized language or imagery and unwelcome sexual attention or
|
||||
advances
|
||||
* Trolling, insulting/derogatory comments, and personal or political attacks
|
||||
* Public or private harassment
|
||||
* Publishing others' private information, such as a physical or electronic
|
||||
address, without explicit permission
|
||||
* Other conduct which could reasonably be considered inappropriate in a
|
||||
professional setting
|
||||
|
||||
## Our Responsibilities
|
||||
|
||||
Project maintainers are responsible for clarifying the standards of acceptable
|
||||
behavior and are expected to take appropriate and fair corrective action in
|
||||
response to any instances of unacceptable behavior.
|
||||
|
||||
Project maintainers have the right and responsibility to remove, edit, or
|
||||
reject comments, commits, code, wiki edits, issues, and other contributions
|
||||
that are not aligned to this Code of Conduct, or to ban temporarily or
|
||||
permanently any contributor for other behaviors that they deem inappropriate,
|
||||
threatening, offensive, or harmful.
|
||||
|
||||
## Scope
|
||||
|
||||
This Code of Conduct applies within all project spaces, and it also applies when
|
||||
an individual is representing the project or its community in public spaces.
|
||||
Examples of representing a project or community include using an official
|
||||
project e-mail address, posting via an official social media account, or acting
|
||||
as an appointed representative at an online or offline event. Representation of
|
||||
a project may be further defined and clarified by project maintainers.
|
||||
|
||||
This Code of Conduct also applies outside the project spaces when there is a
|
||||
reasonable belief that an individual's behavior may have a negative impact on
|
||||
the project or its community.
|
||||
|
||||
## Enforcement
|
||||
|
||||
Instances of abusive, harassing, or otherwise unacceptable behavior may be
|
||||
reported by contacting the project team at <opensource-conduct@meta.com>. All
|
||||
complaints will be reviewed and investigated and will result in a response that
|
||||
is deemed necessary and appropriate to the circumstances. The project team is
|
||||
obligated to maintain confidentiality with regard to the reporter of an incident.
|
||||
Further details of specific enforcement policies may be posted separately.
|
||||
|
||||
Project maintainers who do not follow or enforce the Code of Conduct in good
|
||||
faith may face temporary or permanent repercussions as determined by other
|
||||
members of the project's leadership.
|
||||
|
||||
## Attribution
|
||||
|
||||
This Code of Conduct is adapted from the [Contributor Covenant][homepage], version 1.4,
|
||||
available at https://www.contributor-covenant.org/version/1/4/code-of-conduct.html
|
||||
|
||||
[homepage]: https://www.contributor-covenant.org
|
||||
|
||||
For answers to common questions about this code of conduct, see
|
||||
https://www.contributor-covenant.org/faq
|
||||
@@ -1,31 +0,0 @@
|
||||
# Contributing to vggt
|
||||
We want to make contributing to this project as easy and transparent as
|
||||
possible.
|
||||
|
||||
## Pull Requests
|
||||
We actively welcome your pull requests.
|
||||
|
||||
1. Fork the repo and create your branch from `main`.
|
||||
2. If you've added code that should be tested, add tests.
|
||||
3. If you've changed APIs, update the documentation.
|
||||
4. Ensure the test suite passes.
|
||||
5. Make sure your code lints.
|
||||
6. If you haven't already, complete the Contributor License Agreement ("CLA").
|
||||
|
||||
## Contributor License Agreement ("CLA")
|
||||
In order to accept your pull request, we need you to submit a CLA. You only need
|
||||
to do this once to work on any of Facebook's open source projects.
|
||||
|
||||
Complete your CLA here: <https://code.facebook.com/cla>
|
||||
|
||||
## Issues
|
||||
We use GitHub issues to track public bugs. Please ensure your description is
|
||||
clear and has sufficient instructions to be able to reproduce the issue.
|
||||
|
||||
Facebook has a [bounty program](https://www.facebook.com/whitehat/) for the safe
|
||||
disclosure of security bugs. In those cases, please go through the process
|
||||
outlined on that page and do not file a public issue.
|
||||
|
||||
## License
|
||||
By contributing to vggt, you agree that your contributions will be licensed
|
||||
under the LICENSE file in the root directory of this source tree.
|
||||
@@ -1,399 +0,0 @@
|
||||
Attribution-NonCommercial 4.0 International
|
||||
|
||||
=======================================================================
|
||||
|
||||
Creative Commons Corporation ("Creative Commons") is not a law firm and
|
||||
does not provide legal services or legal advice. Distribution of
|
||||
Creative Commons public licenses does not create a lawyer-client or
|
||||
other relationship. Creative Commons makes its licenses and related
|
||||
information available on an "as-is" basis. Creative Commons gives no
|
||||
warranties regarding its licenses, any material licensed under their
|
||||
terms and conditions, or any related information. Creative Commons
|
||||
disclaims all liability for damages resulting from their use to the
|
||||
fullest extent possible.
|
||||
|
||||
Using Creative Commons Public Licenses
|
||||
|
||||
Creative Commons public licenses provide a standard set of terms and
|
||||
conditions that creators and other rights holders may use to share
|
||||
original works of authorship and other material subject to copyright
|
||||
and certain other rights specified in the public license below. The
|
||||
following considerations are for informational purposes only, are not
|
||||
exhaustive, and do not form part of our licenses.
|
||||
|
||||
Considerations for licensors: Our public licenses are
|
||||
intended for use by those authorized to give the public
|
||||
permission to use material in ways otherwise restricted by
|
||||
copyright and certain other rights. Our licenses are
|
||||
irrevocable. Licensors should read and understand the terms
|
||||
and conditions of the license they choose before applying it.
|
||||
Licensors should also secure all rights necessary before
|
||||
applying our licenses so that the public can reuse the
|
||||
material as expected. Licensors should clearly mark any
|
||||
material not subject to the license. This includes other CC-
|
||||
licensed material, or material used under an exception or
|
||||
limitation to copyright. More considerations for licensors:
|
||||
wiki.creativecommons.org/Considerations_for_licensors
|
||||
|
||||
Considerations for the public: By using one of our public
|
||||
licenses, a licensor grants the public permission to use the
|
||||
licensed material under specified terms and conditions. If
|
||||
the licensor's permission is not necessary for any reason--for
|
||||
example, because of any applicable exception or limitation to
|
||||
copyright--then that use is not regulated by the license. Our
|
||||
licenses grant only permissions under copyright and certain
|
||||
other rights that a licensor has authority to grant. Use of
|
||||
the licensed material may still be restricted for other
|
||||
reasons, including because others have copyright or other
|
||||
rights in the material. A licensor may make special requests,
|
||||
such as asking that all changes be marked or described.
|
||||
Although not required by our licenses, you are encouraged to
|
||||
respect those requests where reasonable. More_considerations
|
||||
for the public:
|
||||
wiki.creativecommons.org/Considerations_for_licensees
|
||||
|
||||
=======================================================================
|
||||
|
||||
Creative Commons Attribution-NonCommercial 4.0 International Public
|
||||
License
|
||||
|
||||
By exercising the Licensed Rights (defined below), You accept and agree
|
||||
to be bound by the terms and conditions of this Creative Commons
|
||||
Attribution-NonCommercial 4.0 International Public License ("Public
|
||||
License"). To the extent this Public License may be interpreted as a
|
||||
contract, You are granted the Licensed Rights in consideration of Your
|
||||
acceptance of these terms and conditions, and the Licensor grants You
|
||||
such rights in consideration of benefits the Licensor receives from
|
||||
making the Licensed Material available under these terms and
|
||||
conditions.
|
||||
|
||||
Section 1 -- Definitions.
|
||||
|
||||
a. Adapted Material means material subject to Copyright and Similar
|
||||
Rights that is derived from or based upon the Licensed Material
|
||||
and in which the Licensed Material is translated, altered,
|
||||
arranged, transformed, or otherwise modified in a manner requiring
|
||||
permission under the Copyright and Similar Rights held by the
|
||||
Licensor. For purposes of this Public License, where the Licensed
|
||||
Material is a musical work, performance, or sound recording,
|
||||
Adapted Material is always produced where the Licensed Material is
|
||||
synched in timed relation with a moving image.
|
||||
|
||||
b. Adapter's License means the license You apply to Your Copyright
|
||||
and Similar Rights in Your contributions to Adapted Material in
|
||||
accordance with the terms and conditions of this Public License.
|
||||
|
||||
c. Copyright and Similar Rights means copyright and/or similar rights
|
||||
closely related to copyright including, without limitation,
|
||||
performance, broadcast, sound recording, and Sui Generis Database
|
||||
Rights, without regard to how the rights are labeled or
|
||||
categorized. For purposes of this Public License, the rights
|
||||
specified in Section 2(b)(1)-(2) are not Copyright and Similar
|
||||
Rights.
|
||||
d. Effective Technological Measures means those measures that, in the
|
||||
absence of proper authority, may not be circumvented under laws
|
||||
fulfilling obligations under Article 11 of the WIPO Copyright
|
||||
Treaty adopted on December 20, 1996, and/or similar international
|
||||
agreements.
|
||||
|
||||
e. Exceptions and Limitations means fair use, fair dealing, and/or
|
||||
any other exception or limitation to Copyright and Similar Rights
|
||||
that applies to Your use of the Licensed Material.
|
||||
|
||||
f. Licensed Material means the artistic or literary work, database,
|
||||
or other material to which the Licensor applied this Public
|
||||
License.
|
||||
|
||||
g. Licensed Rights means the rights granted to You subject to the
|
||||
terms and conditions of this Public License, which are limited to
|
||||
all Copyright and Similar Rights that apply to Your use of the
|
||||
Licensed Material and that the Licensor has authority to license.
|
||||
|
||||
h. Licensor means the individual(s) or entity(ies) granting rights
|
||||
under this Public License.
|
||||
|
||||
i. NonCommercial means not primarily intended for or directed towards
|
||||
commercial advantage or monetary compensation. For purposes of
|
||||
this Public License, the exchange of the Licensed Material for
|
||||
other material subject to Copyright and Similar Rights by digital
|
||||
file-sharing or similar means is NonCommercial provided there is
|
||||
no payment of monetary compensation in connection with the
|
||||
exchange.
|
||||
|
||||
j. Share means to provide material to the public by any means or
|
||||
process that requires permission under the Licensed Rights, such
|
||||
as reproduction, public display, public performance, distribution,
|
||||
dissemination, communication, or importation, and to make material
|
||||
available to the public including in ways that members of the
|
||||
public may access the material from a place and at a time
|
||||
individually chosen by them.
|
||||
|
||||
k. Sui Generis Database Rights means rights other than copyright
|
||||
resulting from Directive 96/9/EC of the European Parliament and of
|
||||
the Council of 11 March 1996 on the legal protection of databases,
|
||||
as amended and/or succeeded, as well as other essentially
|
||||
equivalent rights anywhere in the world.
|
||||
|
||||
l. You means the individual or entity exercising the Licensed Rights
|
||||
under this Public License. Your has a corresponding meaning.
|
||||
|
||||
Section 2 -- Scope.
|
||||
|
||||
a. License grant.
|
||||
|
||||
1. Subject to the terms and conditions of this Public License,
|
||||
the Licensor hereby grants You a worldwide, royalty-free,
|
||||
non-sublicensable, non-exclusive, irrevocable license to
|
||||
exercise the Licensed Rights in the Licensed Material to:
|
||||
|
||||
a. reproduce and Share the Licensed Material, in whole or
|
||||
in part, for NonCommercial purposes only; and
|
||||
|
||||
b. produce, reproduce, and Share Adapted Material for
|
||||
NonCommercial purposes only.
|
||||
|
||||
2. Exceptions and Limitations. For the avoidance of doubt, where
|
||||
Exceptions and Limitations apply to Your use, this Public
|
||||
License does not apply, and You do not need to comply with
|
||||
its terms and conditions.
|
||||
|
||||
3. Term. The term of this Public License is specified in Section
|
||||
6(a).
|
||||
|
||||
4. Media and formats; technical modifications allowed. The
|
||||
Licensor authorizes You to exercise the Licensed Rights in
|
||||
all media and formats whether now known or hereafter created,
|
||||
and to make technical modifications necessary to do so. The
|
||||
Licensor waives and/or agrees not to assert any right or
|
||||
authority to forbid You from making technical modifications
|
||||
necessary to exercise the Licensed Rights, including
|
||||
technical modifications necessary to circumvent Effective
|
||||
Technological Measures. For purposes of this Public License,
|
||||
simply making modifications authorized by this Section 2(a)
|
||||
(4) never produces Adapted Material.
|
||||
|
||||
5. Downstream recipients.
|
||||
|
||||
a. Offer from the Licensor -- Licensed Material. Every
|
||||
recipient of the Licensed Material automatically
|
||||
receives an offer from the Licensor to exercise the
|
||||
Licensed Rights under the terms and conditions of this
|
||||
Public License.
|
||||
|
||||
b. No downstream restrictions. You may not offer or impose
|
||||
any additional or different terms or conditions on, or
|
||||
apply any Effective Technological Measures to, the
|
||||
Licensed Material if doing so restricts exercise of the
|
||||
Licensed Rights by any recipient of the Licensed
|
||||
Material.
|
||||
|
||||
6. No endorsement. Nothing in this Public License constitutes or
|
||||
may be construed as permission to assert or imply that You
|
||||
are, or that Your use of the Licensed Material is, connected
|
||||
with, or sponsored, endorsed, or granted official status by,
|
||||
the Licensor or others designated to receive attribution as
|
||||
provided in Section 3(a)(1)(A)(i).
|
||||
|
||||
b. Other rights.
|
||||
|
||||
1. Moral rights, such as the right of integrity, are not
|
||||
licensed under this Public License, nor are publicity,
|
||||
privacy, and/or other similar personality rights; however, to
|
||||
the extent possible, the Licensor waives and/or agrees not to
|
||||
assert any such rights held by the Licensor to the limited
|
||||
extent necessary to allow You to exercise the Licensed
|
||||
Rights, but not otherwise.
|
||||
|
||||
2. Patent and trademark rights are not licensed under this
|
||||
Public License.
|
||||
|
||||
3. To the extent possible, the Licensor waives any right to
|
||||
collect royalties from You for the exercise of the Licensed
|
||||
Rights, whether directly or through a collecting society
|
||||
under any voluntary or waivable statutory or compulsory
|
||||
licensing scheme. In all other cases the Licensor expressly
|
||||
reserves any right to collect such royalties, including when
|
||||
the Licensed Material is used other than for NonCommercial
|
||||
purposes.
|
||||
|
||||
Section 3 -- License Conditions.
|
||||
|
||||
Your exercise of the Licensed Rights is expressly made subject to the
|
||||
following conditions.
|
||||
|
||||
a. Attribution.
|
||||
|
||||
1. If You Share the Licensed Material (including in modified
|
||||
form), You must:
|
||||
|
||||
a. retain the following if it is supplied by the Licensor
|
||||
with the Licensed Material:
|
||||
|
||||
i. identification of the creator(s) of the Licensed
|
||||
Material and any others designated to receive
|
||||
attribution, in any reasonable manner requested by
|
||||
the Licensor (including by pseudonym if
|
||||
designated);
|
||||
|
||||
ii. a copyright notice;
|
||||
|
||||
iii. a notice that refers to this Public License;
|
||||
|
||||
iv. a notice that refers to the disclaimer of
|
||||
warranties;
|
||||
|
||||
v. a URI or hyperlink to the Licensed Material to the
|
||||
extent reasonably practicable;
|
||||
|
||||
b. indicate if You modified the Licensed Material and
|
||||
retain an indication of any previous modifications; and
|
||||
|
||||
c. indicate the Licensed Material is licensed under this
|
||||
Public License, and include the text of, or the URI or
|
||||
hyperlink to, this Public License.
|
||||
|
||||
2. You may satisfy the conditions in Section 3(a)(1) in any
|
||||
reasonable manner based on the medium, means, and context in
|
||||
which You Share the Licensed Material. For example, it may be
|
||||
reasonable to satisfy the conditions by providing a URI or
|
||||
hyperlink to a resource that includes the required
|
||||
information.
|
||||
|
||||
3. If requested by the Licensor, You must remove any of the
|
||||
information required by Section 3(a)(1)(A) to the extent
|
||||
reasonably practicable.
|
||||
|
||||
4. If You Share Adapted Material You produce, the Adapter's
|
||||
License You apply must not prevent recipients of the Adapted
|
||||
Material from complying with this Public License.
|
||||
|
||||
Section 4 -- Sui Generis Database Rights.
|
||||
|
||||
Where the Licensed Rights include Sui Generis Database Rights that
|
||||
apply to Your use of the Licensed Material:
|
||||
|
||||
a. for the avoidance of doubt, Section 2(a)(1) grants You the right
|
||||
to extract, reuse, reproduce, and Share all or a substantial
|
||||
portion of the contents of the database for NonCommercial purposes
|
||||
only;
|
||||
|
||||
b. if You include all or a substantial portion of the database
|
||||
contents in a database in which You have Sui Generis Database
|
||||
Rights, then the database in which You have Sui Generis Database
|
||||
Rights (but not its individual contents) is Adapted Material; and
|
||||
|
||||
c. You must comply with the conditions in Section 3(a) if You Share
|
||||
all or a substantial portion of the contents of the database.
|
||||
|
||||
For the avoidance of doubt, this Section 4 supplements and does not
|
||||
replace Your obligations under this Public License where the Licensed
|
||||
Rights include other Copyright and Similar Rights.
|
||||
|
||||
Section 5 -- Disclaimer of Warranties and Limitation of Liability.
|
||||
|
||||
a. UNLESS OTHERWISE SEPARATELY UNDERTAKEN BY THE LICENSOR, TO THE
|
||||
EXTENT POSSIBLE, THE LICENSOR OFFERS THE LICENSED MATERIAL AS-IS
|
||||
AND AS-AVAILABLE, AND MAKES NO REPRESENTATIONS OR WARRANTIES OF
|
||||
ANY KIND CONCERNING THE LICENSED MATERIAL, WHETHER EXPRESS,
|
||||
IMPLIED, STATUTORY, OR OTHER. THIS INCLUDES, WITHOUT LIMITATION,
|
||||
WARRANTIES OF TITLE, MERCHANTABILITY, FITNESS FOR A PARTICULAR
|
||||
PURPOSE, NON-INFRINGEMENT, ABSENCE OF LATENT OR OTHER DEFECTS,
|
||||
ACCURACY, OR THE PRESENCE OR ABSENCE OF ERRORS, WHETHER OR NOT
|
||||
KNOWN OR DISCOVERABLE. WHERE DISCLAIMERS OF WARRANTIES ARE NOT
|
||||
ALLOWED IN FULL OR IN PART, THIS DISCLAIMER MAY NOT APPLY TO YOU.
|
||||
|
||||
b. TO THE EXTENT POSSIBLE, IN NO EVENT WILL THE LICENSOR BE LIABLE
|
||||
TO YOU ON ANY LEGAL THEORY (INCLUDING, WITHOUT LIMITATION,
|
||||
NEGLIGENCE) OR OTHERWISE FOR ANY DIRECT, SPECIAL, INDIRECT,
|
||||
INCIDENTAL, CONSEQUENTIAL, PUNITIVE, EXEMPLARY, OR OTHER LOSSES,
|
||||
COSTS, EXPENSES, OR DAMAGES ARISING OUT OF THIS PUBLIC LICENSE OR
|
||||
USE OF THE LICENSED MATERIAL, EVEN IF THE LICENSOR HAS BEEN
|
||||
ADVISED OF THE POSSIBILITY OF SUCH LOSSES, COSTS, EXPENSES, OR
|
||||
DAMAGES. WHERE A LIMITATION OF LIABILITY IS NOT ALLOWED IN FULL OR
|
||||
IN PART, THIS LIMITATION MAY NOT APPLY TO YOU.
|
||||
|
||||
c. The disclaimer of warranties and limitation of liability provided
|
||||
above shall be interpreted in a manner that, to the extent
|
||||
possible, most closely approximates an absolute disclaimer and
|
||||
waiver of all liability.
|
||||
|
||||
Section 6 -- Term and Termination.
|
||||
|
||||
a. This Public License applies for the term of the Copyright and
|
||||
Similar Rights licensed here. However, if You fail to comply with
|
||||
this Public License, then Your rights under this Public License
|
||||
terminate automatically.
|
||||
|
||||
b. Where Your right to use the Licensed Material has terminated under
|
||||
Section 6(a), it reinstates:
|
||||
|
||||
1. automatically as of the date the violation is cured, provided
|
||||
it is cured within 30 days of Your discovery of the
|
||||
violation; or
|
||||
|
||||
2. upon express reinstatement by the Licensor.
|
||||
|
||||
For the avoidance of doubt, this Section 6(b) does not affect any
|
||||
right the Licensor may have to seek remedies for Your violations
|
||||
of this Public License.
|
||||
|
||||
c. For the avoidance of doubt, the Licensor may also offer the
|
||||
Licensed Material under separate terms or conditions or stop
|
||||
distributing the Licensed Material at any time; however, doing so
|
||||
will not terminate this Public License.
|
||||
|
||||
d. Sections 1, 5, 6, 7, and 8 survive termination of this Public
|
||||
License.
|
||||
|
||||
Section 7 -- Other Terms and Conditions.
|
||||
|
||||
a. The Licensor shall not be bound by any additional or different
|
||||
terms or conditions communicated by You unless expressly agreed.
|
||||
|
||||
b. Any arrangements, understandings, or agreements regarding the
|
||||
Licensed Material not stated herein are separate from and
|
||||
independent of the terms and conditions of this Public License.
|
||||
|
||||
Section 8 -- Interpretation.
|
||||
|
||||
a. For the avoidance of doubt, this Public License does not, and
|
||||
shall not be interpreted to, reduce, limit, restrict, or impose
|
||||
conditions on any use of the Licensed Material that could lawfully
|
||||
be made without permission under this Public License.
|
||||
|
||||
b. To the extent possible, if any provision of this Public License is
|
||||
deemed unenforceable, it shall be automatically reformed to the
|
||||
minimum extent necessary to make it enforceable. If the provision
|
||||
cannot be reformed, it shall be severed from this Public License
|
||||
without affecting the enforceability of the remaining terms and
|
||||
conditions.
|
||||
|
||||
c. No term or condition of this Public License will be waived and no
|
||||
failure to comply consented to unless expressly agreed to by the
|
||||
Licensor.
|
||||
|
||||
d. Nothing in this Public License constitutes or may be interpreted
|
||||
as a limitation upon, or waiver of, any privileges and immunities
|
||||
that apply to the Licensor or You, including from the legal
|
||||
processes of any jurisdiction or authority.
|
||||
|
||||
=======================================================================
|
||||
|
||||
Creative Commons is not a party to its public
|
||||
licenses. Notwithstanding, Creative Commons may elect to apply one of
|
||||
its public licenses to material it publishes and in those instances
|
||||
will be considered the “Licensor.” The text of the Creative Commons
|
||||
public licenses is dedicated to the public domain under the CC0 Public
|
||||
Domain Dedication. Except for the limited purpose of indicating that
|
||||
material is shared under a Creative Commons public license or as
|
||||
otherwise permitted by the Creative Commons policies published at
|
||||
creativecommons.org/policies, Creative Commons does not authorize the
|
||||
use of the trademark "Creative Commons" or any other trademark or logo
|
||||
of Creative Commons without its prior written consent including,
|
||||
without limitation, in connection with any unauthorized modifications
|
||||
to any of its public licenses or any other arrangements,
|
||||
understandings, or agreements concerning use of licensed material. For
|
||||
the avoidance of doubt, this paragraph does not form part of the
|
||||
public licenses.
|
||||
|
||||
Creative Commons may be contacted at creativecommons.org.
|
||||
@@ -1,240 +0,0 @@
|
||||
<div align="center">
|
||||
<h1>VGGT: Visual Geometry Grounded Transformer</h1>
|
||||
|
||||
<a href="https://jytime.github.io/data/VGGT_CVPR25.pdf" target="_blank" rel="noopener noreferrer">
|
||||
<img src="https://img.shields.io/badge/Paper-VGGT" alt="Paper PDF">
|
||||
</a>
|
||||
<a href="https://arxiv.org/abs/2503.11651"><img src="https://img.shields.io/badge/arXiv-2503.11651-b31b1b" alt="arXiv"></a>
|
||||
<a href="https://vgg-t.github.io/"><img src="https://img.shields.io/badge/Project_Page-green" alt="Project Page"></a>
|
||||
<a href='https://huggingface.co/spaces/facebook/vggt'><img src='https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Demo-blue'></a>
|
||||
|
||||
|
||||
**[Visual Geometry Group, University of Oxford](https://www.robots.ox.ac.uk/~vgg/)**; **[Meta AI](https://ai.facebook.com/research/)**
|
||||
|
||||
|
||||
[Jianyuan Wang](https://jytime.github.io/), [Minghao Chen](https://silent-chen.github.io/), [Nikita Karaev](https://nikitakaraevv.github.io/), [Andrea Vedaldi](https://www.robots.ox.ac.uk/~vedaldi/), [Christian Rupprecht](https://chrirupp.github.io/), [David Novotny](https://d-novotny.github.io/)
|
||||
</div>
|
||||
|
||||
```bibtex
|
||||
@inproceedings{wang2025vggt,
|
||||
title={VGGT: Visual Geometry Grounded Transformer},
|
||||
author={Wang, Jianyuan and Chen, Minghao and Karaev, Nikita and Vedaldi, Andrea and Rupprecht, Christian and Novotny, David},
|
||||
booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
|
||||
year={2025}
|
||||
}
|
||||
```
|
||||
|
||||
## Updates
|
||||
- [May 3, 2025] Evaluation code for reproducing our camera pose estimation results on Co3D is now available in the [evaluation](https://github.com/facebookresearch/vggt/tree/evaluation) branch. VGGT+BA implementation is coming.
|
||||
|
||||
|
||||
- [Apr 13, 2025] Training code is being gradually cleaned and uploaded to the [training](https://github.com/facebookresearch/vggt/tree/training) branch. It will be merged into the main branch once finalized.
|
||||
|
||||
## Overview
|
||||
|
||||
Visual Geometry Grounded Transformer (VGGT, CVPR 2025) is a feed-forward neural network that directly infers all key 3D attributes of a scene, including extrinsic and intrinsic camera parameters, point maps, depth maps, and 3D point tracks, **from one, a few, or hundreds of its views, within seconds**.
|
||||
|
||||
|
||||
## Quick Start
|
||||
|
||||
First, clone this repository to your local machine, and install the dependencies (torch, torchvision, numpy, Pillow, and huggingface_hub).
|
||||
|
||||
```bash
|
||||
git clone git@github.com:facebookresearch/vggt.git
|
||||
cd vggt
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
Alternatively, you can install VGGT as a package (<a href="docs/package.md">click here</a> for details).
|
||||
|
||||
|
||||
Now, try the model with just a few lines of code:
|
||||
|
||||
```python
|
||||
import torch
|
||||
from vggt.models.vggt import VGGT
|
||||
from vggt.utils.load_fn import load_and_preprocess_images
|
||||
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
# bfloat16 is supported on Ampere GPUs (Compute Capability 8.0+)
|
||||
dtype = torch.bfloat16 if torch.cuda.get_device_capability()[0] >= 8 else torch.float16
|
||||
|
||||
# Initialize the model and load the pretrained weights.
|
||||
# This will automatically download the model weights the first time it's run, which may take a while.
|
||||
model = VGGT.from_pretrained("facebook/VGGT-1B").to(device)
|
||||
|
||||
# Load and preprocess example images (replace with your own image paths)
|
||||
image_names = ["path/to/imageA.png", "path/to/imageB.png", "path/to/imageC.png"]
|
||||
images = load_and_preprocess_images(image_names).to(device)
|
||||
|
||||
with torch.no_grad():
|
||||
with torch.cuda.amp.autocast(dtype=dtype):
|
||||
# Predict attributes including cameras, depth maps, and point maps.
|
||||
predictions = model(images)
|
||||
```
|
||||
|
||||
The model weights will be automatically downloaded from Hugging Face. If you encounter issues such as slow loading, you can manually download them [here](https://huggingface.co/facebook/VGGT-1B/blob/main/model.pt) and load, or:
|
||||
|
||||
```python
|
||||
model = VGGT()
|
||||
_URL = "https://huggingface.co/facebook/VGGT-1B/resolve/main/model.pt"
|
||||
model.load_state_dict(torch.hub.load_state_dict_from_url(_URL))
|
||||
```
|
||||
|
||||
## Detailed Usage
|
||||
|
||||
You can also optionally choose which attributes (branches) to predict, as shown below. This achieves the same result as the example above. This example uses a batch size of 1 (processing a single scene), but it naturally works for multiple scenes.
|
||||
|
||||
```python
|
||||
from vggt.utils.pose_enc import pose_encoding_to_extri_intri
|
||||
from vggt.utils.geometry import unproject_depth_map_to_point_map
|
||||
|
||||
with torch.no_grad():
|
||||
with torch.cuda.amp.autocast(dtype=dtype):
|
||||
images = images[None] # add batch dimension
|
||||
aggregated_tokens_list, ps_idx = model.aggregator(images)
|
||||
|
||||
# Predict Cameras
|
||||
pose_enc = model.camera_head(aggregated_tokens_list)[-1]
|
||||
# Extrinsic and intrinsic matrices, following OpenCV convention (camera from world)
|
||||
extrinsic, intrinsic = pose_encoding_to_extri_intri(pose_enc, images.shape[-2:])
|
||||
|
||||
# Predict Depth Maps
|
||||
depth_map, depth_conf = model.depth_head(aggregated_tokens_list, images, ps_idx)
|
||||
|
||||
# Predict Point Maps
|
||||
point_map, point_conf = model.point_head(aggregated_tokens_list, images, ps_idx)
|
||||
|
||||
# Construct 3D Points from Depth Maps and Cameras
|
||||
# which usually leads to more accurate 3D points than point map branch
|
||||
point_map_by_unprojection = unproject_depth_map_to_point_map(depth_map.squeeze(0),
|
||||
extrinsic.squeeze(0),
|
||||
intrinsic.squeeze(0))
|
||||
|
||||
# Predict Tracks
|
||||
# choose your own points to track, with shape (N, 2) for one scene
|
||||
query_points = torch.FloatTensor([[100.0, 200.0],
|
||||
[60.72, 259.94]]).to(device)
|
||||
track_list, vis_score, conf_score = model.track_head(aggregated_tokens_list, images, ps_idx, query_points=query_points[None])
|
||||
```
|
||||
|
||||
|
||||
Furthermore, if certain pixels in the input frames are unwanted (e.g., reflective surfaces, sky, or water), you can simply mask them by setting the corresponding pixel values to 0 or 1. Precise segmentation masks aren't necessary - simple bounding box masks work effectively (check this [issue](https://github.com/facebookresearch/vggt/issues/47) for an example).
|
||||
|
||||
|
||||
## Visualization
|
||||
|
||||
We provide multiple ways to visualize your 3D reconstructions and tracking results. Before using these visualization tools, install the required dependencies:
|
||||
|
||||
```bash
|
||||
pip install -r requirements_demo.txt
|
||||
```
|
||||
|
||||
### Interactive 3D Visualization
|
||||
|
||||
**Please note:** VGGT typically reconstructs a scene in less than 1 second. However, visualizing 3D points may take tens of seconds due to third-party rendering, independent of VGGT's processing time. The visualization is slow especially when the number of images is large.
|
||||
|
||||
|
||||
#### Gradio Web Interface
|
||||
|
||||
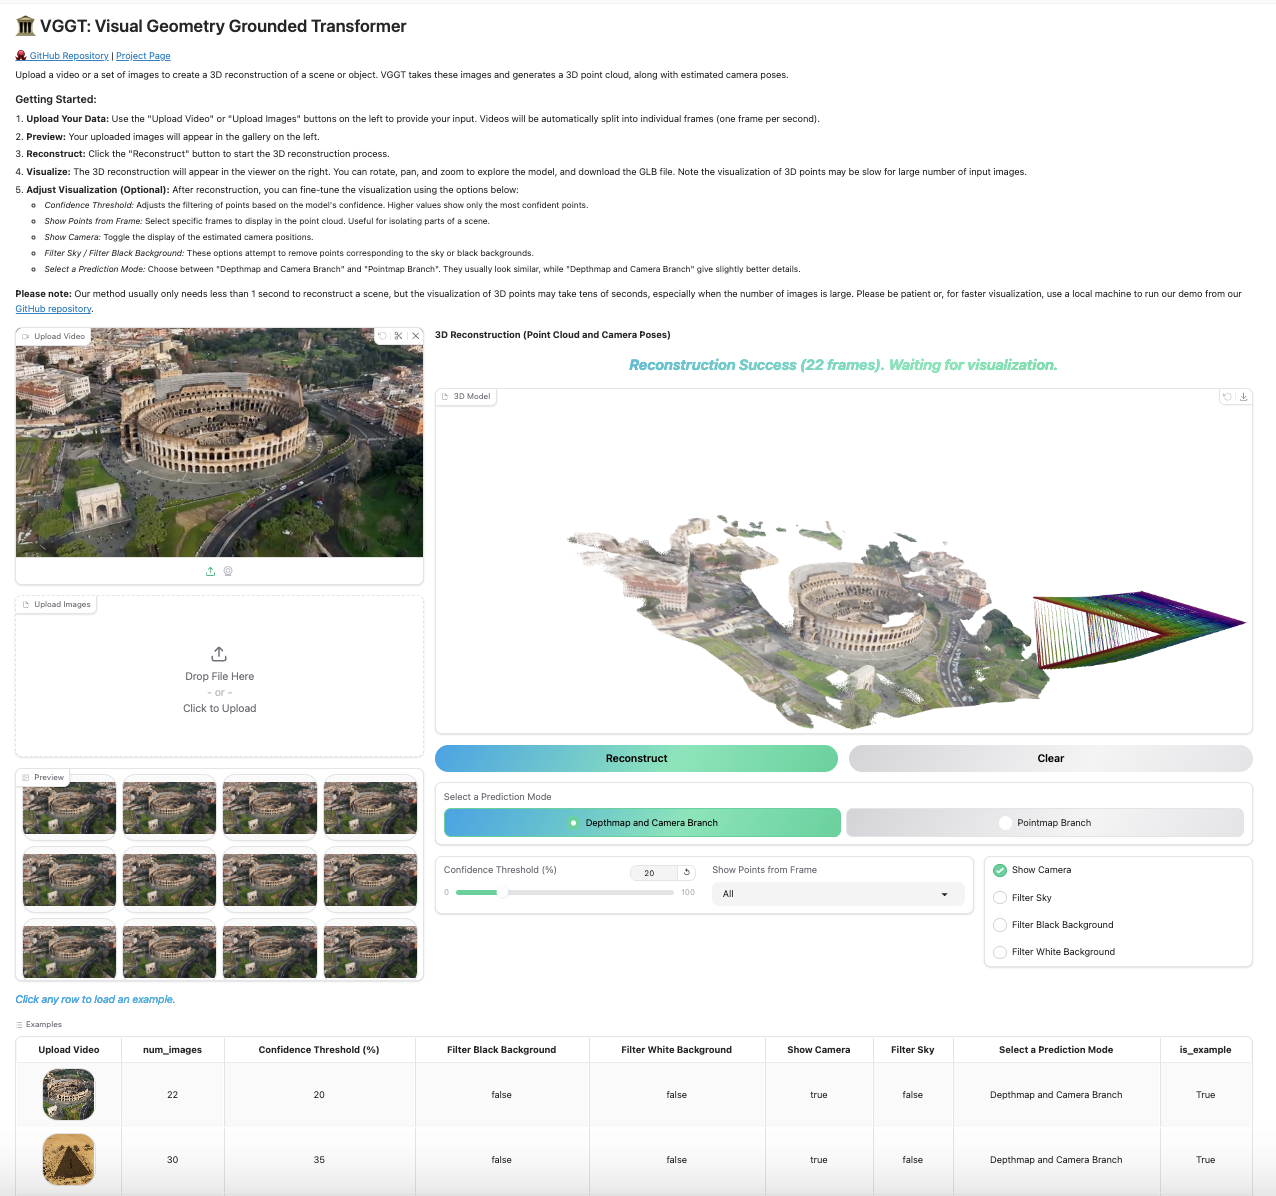
Our Gradio-based interface allows you to upload images/videos, run reconstruction, and interactively explore the 3D scene in your browser. You can launch this in your local machine or try it on [Hugging Face](https://huggingface.co/spaces/facebook/vggt).
|
||||
|
||||
|
||||
```bash
|
||||
python demo_gradio.py
|
||||
```
|
||||
|
||||
<details>
|
||||
<summary>Click to preview the Gradio interactive interface</summary>
|
||||
|
||||
|
||||
</details>
|
||||
|
||||
|
||||
#### Viser 3D Viewer
|
||||
|
||||
Run the following command to run reconstruction and visualize the point clouds in viser. Note this script requires a path to a folder containing images. It assumes only image files under the folder. You can set `--use_point_map` to use the point cloud from the point map branch, instead of the depth-based point cloud.
|
||||
|
||||
```bash
|
||||
python demo_viser.py --image_folder path/to/your/images/folder
|
||||
```
|
||||
|
||||
|
||||
### Track Visualization
|
||||
|
||||
To visualize point tracks across multiple images:
|
||||
|
||||
```python
|
||||
from vggt.utils.visual_track import visualize_tracks_on_images
|
||||
track = track_list[-1]
|
||||
visualize_tracks_on_images(images, track, (conf_score>0.2) & (vis_score>0.2), out_dir="track_visuals")
|
||||
```
|
||||
This plots the tracks on the images and saves them to the specified output directory.
|
||||
|
||||
|
||||
## Single-view Reconstruction
|
||||
|
||||
Our model shows surprisingly good performance on single-view reconstruction, although it was never trained for this task. The model does not need to duplicate the single-view image to a pair, instead, it can directly infer the 3D structure from the tokens of the single view image. Feel free to try it with our demos above, which naturally works for single-view reconstruction.
|
||||
|
||||
|
||||
We did not quantitatively test monocular depth estimation performance ourselves, but [@kabouzeid](https://github.com/kabouzeid) generously provided a comparison of VGGT to recent methods [here](https://github.com/facebookresearch/vggt/issues/36). VGGT shows competitive or better results compared to state-of-the-art monocular approaches such as DepthAnything v2 or MoGe, despite never being explicitly trained for single-view tasks.
|
||||
|
||||
|
||||
|
||||
## Runtime and GPU Memory
|
||||
|
||||
We benchmark the runtime and GPU memory usage of VGGT's aggregator on a single NVIDIA H100 GPU across various input sizes.
|
||||
|
||||
| **Input Frames** | 1 | 2 | 4 | 8 | 10 | 20 | 50 | 100 | 200 |
|
||||
|:----------------:|:-:|:-:|:-:|:-:|:--:|:--:|:--:|:---:|:---:|
|
||||
| **Time (s)** | 0.04 | 0.05 | 0.07 | 0.11 | 0.14 | 0.31 | 1.04 | 3.12 | 8.75 |
|
||||
| **Memory (GB)** | 1.88 | 2.07 | 2.45 | 3.23 | 3.63 | 5.58 | 11.41 | 21.15 | 40.63 |
|
||||
|
||||
Note that these results were obtained using Flash Attention 3, which is faster than the default Flash Attention 2 implementation while maintaining almost the same memory usage. Feel free to compile Flash Attention 3 from source to get better performance.
|
||||
|
||||
|
||||
## Research Progression
|
||||
|
||||
Our work builds upon a series of previous research projects. If you're interested in understanding how our research evolved, check out our previous works:
|
||||
|
||||
|
||||
<table border="0" cellspacing="0" cellpadding="0">
|
||||
<tr>
|
||||
<td align="left">
|
||||
<a href="https://github.com/jytime/Deep-SfM-Revisited">Deep SfM Revisited</a>
|
||||
</td>
|
||||
<td style="white-space: pre;">──┐</td>
|
||||
<td></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="left">
|
||||
<a href="https://github.com/facebookresearch/PoseDiffusion">PoseDiffusion</a>
|
||||
</td>
|
||||
<td style="white-space: pre;">─────►</td>
|
||||
<td>
|
||||
<a href="https://github.com/facebookresearch/vggsfm">VGGSfM</a> ──►
|
||||
<a href="https://github.com/facebookresearch/vggt">VGGT</a>
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="left">
|
||||
<a href="https://github.com/facebookresearch/co-tracker">CoTracker</a>
|
||||
</td>
|
||||
<td style="white-space: pre;">──┘</td>
|
||||
<td></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
## Acknowledgements
|
||||
|
||||
Thanks to these great repositories: [PoseDiffusion](https://github.com/facebookresearch/PoseDiffusion), [VGGSfM](https://github.com/facebookresearch/vggsfm), [CoTracker](https://github.com/facebookresearch/co-tracker), [DINOv2](https://github.com/facebookresearch/dinov2), [Dust3r](https://github.com/naver/dust3r), [Moge](https://github.com/microsoft/moge), [PyTorch3D](https://github.com/facebookresearch/pytorch3d), [Sky Segmentation](https://github.com/xiongzhu666/Sky-Segmentation-and-Post-processing), [Depth Anything V2](https://github.com/DepthAnything/Depth-Anything-V2), [Metric3D](https://github.com/YvanYin/Metric3D) and many other inspiring works in the community.
|
||||
|
||||
## Checklist
|
||||
|
||||
- [ ] Release the training code
|
||||
- [ ] Release VGGT-500M and VGGT-200M
|
||||
|
||||
|
||||
## License
|
||||
See the [LICENSE](./LICENSE.txt) file for details about the license under which this code is made available.
|
||||
@@ -1,327 +0,0 @@
|
||||
# Copyright (c) Meta Platforms, Inc. and affiliates.
|
||||
# All rights reserved.
|
||||
#
|
||||
# This source code is licensed under the license found in the
|
||||
# LICENSE file in the root directory of this source tree.
|
||||
|
||||
import random
|
||||
import numpy as np
|
||||
import glob
|
||||
import os
|
||||
import copy
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
|
||||
# Configure CUDA settings
|
||||
torch.backends.cudnn.enabled = True
|
||||
torch.backends.cudnn.benchmark = True
|
||||
torch.backends.cudnn.deterministic = False
|
||||
|
||||
import argparse
|
||||
from pathlib import Path
|
||||
import trimesh
|
||||
import pycolmap
|
||||
|
||||
|
||||
from vggt.models.vggt import VGGT
|
||||
from vggt.utils.load_fn import load_and_preprocess_images_square
|
||||
from vggt.utils.pose_enc import pose_encoding_to_extri_intri
|
||||
from vggt.utils.geometry import unproject_depth_map_to_point_map
|
||||
from vggt.utils.helper import create_pixel_coordinate_grid, randomly_limit_trues
|
||||
from vggt.dependency.track_predict import predict_tracks
|
||||
from vggt.dependency.np_to_pycolmap import batch_np_matrix_to_pycolmap, batch_np_matrix_to_pycolmap_wo_track
|
||||
|
||||
|
||||
# TODO: add support for masks
|
||||
# TODO: add iterative BA
|
||||
# TODO: add support for radial distortion, which needs extra_params
|
||||
# TODO: test with more cases
|
||||
# TODO: test different camera types
|
||||
|
||||
|
||||
def parse_args():
|
||||
parser = argparse.ArgumentParser(description="VGGT Demo")
|
||||
parser.add_argument("--scene_dir", type=str, required=True, help="Directory containing the scene images")
|
||||
parser.add_argument("--seed", type=int, default=42, help="Random seed for reproducibility")
|
||||
parser.add_argument("--use_ba", action="store_true", default=False, help="Use BA for reconstruction")
|
||||
######### BA parameters #########
|
||||
parser.add_argument(
|
||||
"--max_reproj_error", type=float, default=8.0, help="Maximum reprojection error for reconstruction"
|
||||
)
|
||||
parser.add_argument("--shared_camera", action="store_true", default=False, help="Use shared camera for all images")
|
||||
parser.add_argument("--camera_type", type=str, default="SIMPLE_PINHOLE", help="Camera type for reconstruction")
|
||||
parser.add_argument("--vis_thresh", type=float, default=0.2, help="Visibility threshold for tracks")
|
||||
parser.add_argument("--query_frame_num", type=int, default=5, help="Number of frames to query")
|
||||
parser.add_argument("--max_query_pts", type=int, default=2048, help="Maximum number of query points")
|
||||
parser.add_argument(
|
||||
"--fine_tracking", action="store_true", default=True, help="Use fine tracking (slower but more accurate)"
|
||||
)
|
||||
return parser.parse_args()
|
||||
|
||||
|
||||
def run_VGGT(model, images, dtype, resolution=518):
|
||||
# images: [B, 3, H, W]
|
||||
|
||||
assert len(images.shape) == 4
|
||||
assert images.shape[1] == 3
|
||||
|
||||
# hard-coded to use 518 for VGGT
|
||||
images = F.interpolate(images, size=(resolution, resolution), mode="bilinear", align_corners=False)
|
||||
|
||||
with torch.no_grad():
|
||||
with torch.cuda.amp.autocast(dtype=dtype):
|
||||
images = images[None] # add batch dimension
|
||||
aggregated_tokens_list, ps_idx = model.aggregator(images)
|
||||
|
||||
# Predict Cameras
|
||||
pose_enc = model.camera_head(aggregated_tokens_list)[-1]
|
||||
# Extrinsic and intrinsic matrices, following OpenCV convention (camera from world)
|
||||
extrinsic, intrinsic = pose_encoding_to_extri_intri(pose_enc, images.shape[-2:])
|
||||
# Predict Depth Maps
|
||||
depth_map, depth_conf = model.depth_head(aggregated_tokens_list, images, ps_idx)
|
||||
|
||||
extrinsic = extrinsic.squeeze(0).cpu().numpy()
|
||||
intrinsic = intrinsic.squeeze(0).cpu().numpy()
|
||||
depth_map = depth_map.squeeze(0).cpu().numpy()
|
||||
depth_conf = depth_conf.squeeze(0).cpu().numpy()
|
||||
return extrinsic, intrinsic, depth_map, depth_conf
|
||||
|
||||
|
||||
def demo_fn(args):
|
||||
# Print configuration
|
||||
print("Arguments:", vars(args))
|
||||
|
||||
# Set seed for reproducibility
|
||||
np.random.seed(args.seed)
|
||||
torch.manual_seed(args.seed)
|
||||
random.seed(args.seed)
|
||||
if torch.cuda.is_available():
|
||||
torch.cuda.manual_seed(args.seed)
|
||||
torch.cuda.manual_seed_all(args.seed) # for multi-GPU
|
||||
print(f"Setting seed as: {args.seed}")
|
||||
|
||||
# Set device and dtype
|
||||
dtype = torch.bfloat16 if torch.cuda.get_device_capability()[0] >= 8 else torch.float16
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
print(f"Using device: {device}")
|
||||
print(f"Using dtype: {dtype}")
|
||||
|
||||
# Run VGGT for camera and depth estimation
|
||||
model = VGGT()
|
||||
_URL = "https://huggingface.co/facebook/VGGT-1B/resolve/main/model.pt"
|
||||
model.load_state_dict(torch.hub.load_state_dict_from_url(_URL))
|
||||
model.eval()
|
||||
model = model.to(device)
|
||||
print(f"Model loaded")
|
||||
|
||||
# Get image paths and preprocess them
|
||||
image_dir = os.path.join(args.scene_dir, "images")
|
||||
image_path_list = glob.glob(os.path.join(image_dir, "*"))
|
||||
if len(image_path_list) == 0:
|
||||
raise ValueError(f"No images found in {image_dir}")
|
||||
base_image_path_list = [os.path.basename(path) for path in image_path_list]
|
||||
|
||||
# Load images and original coordinates
|
||||
# Load Image in 1024, while running VGGT with 518
|
||||
vggt_fixed_resolution = 518
|
||||
img_load_resolution = 1024
|
||||
|
||||
images, original_coords = load_and_preprocess_images_square(image_path_list, img_load_resolution)
|
||||
images = images.to(device)
|
||||
original_coords = original_coords.to(device)
|
||||
print(f"Loaded {len(images)} images from {image_dir}")
|
||||
|
||||
# Run VGGT to estimate camera and depth
|
||||
# Run with 518x518 images
|
||||
extrinsic, intrinsic, depth_map, depth_conf = run_VGGT(model, images, dtype, vggt_fixed_resolution)
|
||||
points_3d = unproject_depth_map_to_point_map(depth_map, extrinsic, intrinsic)
|
||||
|
||||
if args.use_ba:
|
||||
image_size = np.array(images.shape[-2:])
|
||||
scale = img_load_resolution / vggt_fixed_resolution
|
||||
shared_camera = args.shared_camera
|
||||
|
||||
with torch.cuda.amp.autocast(dtype=dtype):
|
||||
# Predicting Tracks
|
||||
# Using VGGSfM tracker instead of VGGT tracker for efficiency
|
||||
# VGGT tracker requires multiple backbone runs to query different frames (this is a problem caused by the training process)
|
||||
# Will be fixed in VGGT v2
|
||||
|
||||
# You can also change the pred_tracks to tracks from any other methods
|
||||
# e.g., from COLMAP, from CoTracker, or by chaining 2D matches from Lightglue/LoFTR.
|
||||
pred_tracks, pred_vis_scores, pred_confs, points_3d, points_rgb = predict_tracks(
|
||||
images,
|
||||
conf=depth_conf,
|
||||
points_3d=points_3d,
|
||||
masks=None,
|
||||
max_query_pts=args.max_query_pts,
|
||||
query_frame_num=args.query_frame_num,
|
||||
keypoint_extractor="aliked+sp",
|
||||
fine_tracking=args.fine_tracking,
|
||||
)
|
||||
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
# rescale the intrinsic matrix from 518 to 1024
|
||||
intrinsic[:, :2, :] *= scale
|
||||
track_mask = pred_vis_scores > args.vis_thresh
|
||||
|
||||
# TODO: radial distortion, iterative BA, masks
|
||||
reconstruction, valid_track_mask = batch_np_matrix_to_pycolmap(
|
||||
points_3d,
|
||||
extrinsic,
|
||||
intrinsic,
|
||||
pred_tracks,
|
||||
image_size,
|
||||
masks=track_mask,
|
||||
max_reproj_error=args.max_reproj_error,
|
||||
shared_camera=shared_camera,
|
||||
camera_type=args.camera_type,
|
||||
points_rgb=points_rgb,
|
||||
)
|
||||
|
||||
if reconstruction is None:
|
||||
raise ValueError("No reconstruction can be built with BA")
|
||||
|
||||
# Bundle Adjustment
|
||||
ba_options = pycolmap.BundleAdjustmentOptions()
|
||||
pycolmap.bundle_adjustment(reconstruction, ba_options)
|
||||
|
||||
reconstruction_resolution = img_load_resolution
|
||||
else:
|
||||
conf_thres_value = 5 # hard-coded to 5
|
||||
max_points_for_colmap = 100000 # randomly sample 3D points
|
||||
shared_camera = False # in the feedforward manner, we do not support shared camera
|
||||
camera_type = "PINHOLE" # in the feedforward manner, we only support PINHOLE camera
|
||||
|
||||
image_size = np.array([vggt_fixed_resolution, vggt_fixed_resolution])
|
||||
num_frames, height, width, _ = points_3d.shape
|
||||
|
||||
points_rgb = F.interpolate(
|
||||
images, size=(vggt_fixed_resolution, vggt_fixed_resolution), mode="bilinear", align_corners=False
|
||||
)
|
||||
points_rgb = (points_rgb.cpu().numpy() * 255).astype(np.uint8)
|
||||
points_rgb = points_rgb.transpose(0, 2, 3, 1)
|
||||
|
||||
# (S, H, W, 3), with x, y coordinates and frame indices
|
||||
points_xyf = create_pixel_coordinate_grid(num_frames, height, width)
|
||||
|
||||
conf_mask = depth_conf >= conf_thres_value
|
||||
# at most writing 100000 3d points to colmap reconstruction object
|
||||
conf_mask = randomly_limit_trues(conf_mask, max_points_for_colmap)
|
||||
|
||||
points_3d = points_3d[conf_mask]
|
||||
points_xyf = points_xyf[conf_mask]
|
||||
points_rgb = points_rgb[conf_mask]
|
||||
|
||||
print("Converting to COLMAP format")
|
||||
reconstruction = batch_np_matrix_to_pycolmap_wo_track(
|
||||
points_3d,
|
||||
points_xyf,
|
||||
points_rgb,
|
||||
extrinsic,
|
||||
intrinsic,
|
||||
image_size,
|
||||
shared_camera=shared_camera,
|
||||
camera_type=camera_type,
|
||||
)
|
||||
|
||||
reconstruction_resolution = vggt_fixed_resolution
|
||||
|
||||
reconstruction = rename_colmap_recons_and_rescale_camera(
|
||||
reconstruction,
|
||||
base_image_path_list,
|
||||
original_coords.cpu().numpy(),
|
||||
img_size=reconstruction_resolution,
|
||||
shift_point2d_to_original_res=True,
|
||||
shared_camera=shared_camera,
|
||||
)
|
||||
|
||||
print(f"Saving reconstruction to {args.scene_dir}/sparse")
|
||||
sparse_reconstruction_dir = os.path.join(args.scene_dir, "sparse")
|
||||
os.makedirs(sparse_reconstruction_dir, exist_ok=True)
|
||||
reconstruction.write(sparse_reconstruction_dir)
|
||||
|
||||
# Save point cloud for fast visualization
|
||||
trimesh.PointCloud(points_3d, colors=points_rgb).export(os.path.join(args.scene_dir, "sparse/points.ply"))
|
||||
|
||||
return True
|
||||
|
||||
|
||||
def rename_colmap_recons_and_rescale_camera(
|
||||
reconstruction, image_paths, original_coords, img_size, shift_point2d_to_original_res=False, shared_camera=False
|
||||
):
|
||||
rescale_camera = True
|
||||
|
||||
for pyimageid in reconstruction.images:
|
||||
# Reshaped the padded&resized image to the original size
|
||||
# Rename the images to the original names
|
||||
pyimage = reconstruction.images[pyimageid]
|
||||
pycamera = reconstruction.cameras[pyimage.camera_id]
|
||||
pyimage.name = image_paths[pyimageid - 1]
|
||||
|
||||
if rescale_camera:
|
||||
# Rescale the camera parameters
|
||||
pred_params = copy.deepcopy(pycamera.params)
|
||||
|
||||
real_image_size = original_coords[pyimageid - 1, -2:]
|
||||
resize_ratio = max(real_image_size) / img_size
|
||||
pred_params = pred_params * resize_ratio
|
||||
real_pp = real_image_size / 2
|
||||
pred_params[-2:] = real_pp # center of the image
|
||||
|
||||
pycamera.params = pred_params
|
||||
pycamera.width = real_image_size[0]
|
||||
pycamera.height = real_image_size[1]
|
||||
|
||||
if shift_point2d_to_original_res:
|
||||
# Also shift the point2D to original resolution
|
||||
top_left = original_coords[pyimageid - 1, :2]
|
||||
|
||||
for point2D in pyimage.points2D:
|
||||
point2D.xy = (point2D.xy - top_left) * resize_ratio
|
||||
|
||||
if shared_camera:
|
||||
# If shared_camera, all images share the same camera
|
||||
# no need to rescale any more
|
||||
rescale_camera = False
|
||||
|
||||
return reconstruction
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
args = parse_args()
|
||||
with torch.no_grad():
|
||||
demo_fn(args)
|
||||
|
||||
|
||||
# Work in Progress (WIP)
|
||||
|
||||
"""
|
||||
VGGT Runner Script
|
||||
=================
|
||||
|
||||
A script to run the VGGT model for 3D reconstruction from image sequences.
|
||||
|
||||
Directory Structure
|
||||
------------------
|
||||
Input:
|
||||
input_folder/
|
||||
└── images/ # Source images for reconstruction
|
||||
|
||||
Output:
|
||||
output_folder/
|
||||
├── images/
|
||||
├── sparse/ # Reconstruction results
|
||||
│ ├── cameras.bin # Camera parameters (COLMAP format)
|
||||
│ ├── images.bin # Pose for each image (COLMAP format)
|
||||
│ ├── points3D.bin # 3D points (COLMAP format)
|
||||
│ └── points.ply # Point cloud visualization file
|
||||
└── visuals/ # Visualization outputs TODO
|
||||
|
||||
Key Features
|
||||
-----------
|
||||
• Dual-mode Support: Run reconstructions using either VGGT or VGGT+BA
|
||||
• Resolution Preservation: Maintains original image resolution in camera parameters and tracks
|
||||
• COLMAP Compatibility: Exports results in standard COLMAP sparse reconstruction format
|
||||
"""
|
||||
@@ -1,690 +0,0 @@
|
||||
# Copyright (c) Meta Platforms, Inc. and affiliates.
|
||||
# All rights reserved.
|
||||
#
|
||||
# This source code is licensed under the license found in the
|
||||
# LICENSE file in the root directory of this source tree.
|
||||
|
||||
import os
|
||||
import cv2
|
||||
import torch
|
||||
import numpy as np
|
||||
import gradio as gr
|
||||
import sys
|
||||
import shutil
|
||||
from datetime import datetime
|
||||
import glob
|
||||
import gc
|
||||
import time
|
||||
|
||||
sys.path.append("vggt/")
|
||||
|
||||
from visual_util import predictions_to_glb
|
||||
from vggt.models.vggt import VGGT
|
||||
from vggt.utils.load_fn import load_and_preprocess_images
|
||||
from vggt.utils.pose_enc import pose_encoding_to_extri_intri
|
||||
from vggt.utils.geometry import unproject_depth_map_to_point_map
|
||||
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
|
||||
print("Initializing and loading VGGT model...")
|
||||
# model = VGGT.from_pretrained("facebook/VGGT-1B") # another way to load the model
|
||||
|
||||
model = VGGT()
|
||||
_URL = "https://huggingface.co/facebook/VGGT-1B/resolve/main/model.pt"
|
||||
model.load_state_dict(torch.hub.load_state_dict_from_url(_URL))
|
||||
|
||||
|
||||
model.eval()
|
||||
model = model.to(device)
|
||||
|
||||
|
||||
# -------------------------------------------------------------------------
|
||||
# 1) Core model inference
|
||||
# -------------------------------------------------------------------------
|
||||
def run_model(target_dir, model) -> dict:
|
||||
"""
|
||||
Run the VGGT model on images in the 'target_dir/images' folder and return predictions.
|
||||
"""
|
||||
print(f"Processing images from {target_dir}")
|
||||
|
||||
# Device check
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
if not torch.cuda.is_available():
|
||||
raise ValueError("CUDA is not available. Check your environment.")
|
||||
|
||||
# Move model to device
|
||||
model = model.to(device)
|
||||
model.eval()
|
||||
|
||||
# Load and preprocess images
|
||||
image_names = glob.glob(os.path.join(target_dir, "images", "*"))
|
||||
image_names = sorted(image_names)
|
||||
print(f"Found {len(image_names)} images")
|
||||
if len(image_names) == 0:
|
||||
raise ValueError("No images found. Check your upload.")
|
||||
|
||||
images = load_and_preprocess_images(image_names).to(device)
|
||||
print(f"Preprocessed images shape: {images.shape}")
|
||||
|
||||
# Run inference
|
||||
print("Running inference...")
|
||||
dtype = torch.bfloat16 if torch.cuda.get_device_capability()[0] >= 8 else torch.float16
|
||||
|
||||
with torch.no_grad():
|
||||
with torch.cuda.amp.autocast(dtype=dtype):
|
||||
predictions = model(images)
|
||||
|
||||
# Convert pose encoding to extrinsic and intrinsic matrices
|
||||
print("Converting pose encoding to extrinsic and intrinsic matrices...")
|
||||
extrinsic, intrinsic = pose_encoding_to_extri_intri(predictions["pose_enc"], images.shape[-2:])
|
||||
predictions["extrinsic"] = extrinsic
|
||||
predictions["intrinsic"] = intrinsic
|
||||
|
||||
# Convert tensors to numpy
|
||||
for key in predictions.keys():
|
||||
if isinstance(predictions[key], torch.Tensor):
|
||||
predictions[key] = predictions[key].cpu().numpy().squeeze(0) # remove batch dimension
|
||||
|
||||
# Generate world points from depth map
|
||||
print("Computing world points from depth map...")
|
||||
depth_map = predictions["depth"] # (S, H, W, 1)
|
||||
world_points = unproject_depth_map_to_point_map(depth_map, predictions["extrinsic"], predictions["intrinsic"])
|
||||
predictions["world_points_from_depth"] = world_points
|
||||
|
||||
# Clean up
|
||||
torch.cuda.empty_cache()
|
||||
return predictions
|
||||
|
||||
|
||||
# -------------------------------------------------------------------------
|
||||
# 2) Handle uploaded video/images --> produce target_dir + images
|
||||
# -------------------------------------------------------------------------
|
||||
def handle_uploads(input_video, input_images):
|
||||
"""
|
||||
Create a new 'target_dir' + 'images' subfolder, and place user-uploaded
|
||||
images or extracted frames from video into it. Return (target_dir, image_paths).
|
||||
"""
|
||||
start_time = time.time()
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
# Create a unique folder name
|
||||
timestamp = datetime.now().strftime("%Y%m%d_%H%M%S_%f")
|
||||
target_dir = f"input_images_{timestamp}"
|
||||
target_dir_images = os.path.join(target_dir, "images")
|
||||
|
||||
# Clean up if somehow that folder already exists
|
||||
if os.path.exists(target_dir):
|
||||
shutil.rmtree(target_dir)
|
||||
os.makedirs(target_dir)
|
||||
os.makedirs(target_dir_images)
|
||||
|
||||
image_paths = []
|
||||
|
||||
# --- Handle images ---
|
||||
if input_images is not None:
|
||||
for file_data in input_images:
|
||||
if isinstance(file_data, dict) and "name" in file_data:
|
||||
file_path = file_data["name"]
|
||||
else:
|
||||
file_path = file_data
|
||||
dst_path = os.path.join(target_dir_images, os.path.basename(file_path))
|
||||
shutil.copy(file_path, dst_path)
|
||||
image_paths.append(dst_path)
|
||||
|
||||
# --- Handle video ---
|
||||
if input_video is not None:
|
||||
if isinstance(input_video, dict) and "name" in input_video:
|
||||
video_path = input_video["name"]
|
||||
else:
|
||||
video_path = input_video
|
||||
|
||||
vs = cv2.VideoCapture(video_path)
|
||||
fps = vs.get(cv2.CAP_PROP_FPS)
|
||||
frame_interval = int(fps * 1) # 1 frame/sec
|
||||
|
||||
count = 0
|
||||
video_frame_num = 0
|
||||
while True:
|
||||
gotit, frame = vs.read()
|
||||
if not gotit:
|
||||
break
|
||||
count += 1
|
||||
if count % frame_interval == 0:
|
||||
image_path = os.path.join(target_dir_images, f"{video_frame_num:06}.png")
|
||||
cv2.imwrite(image_path, frame)
|
||||
image_paths.append(image_path)
|
||||
video_frame_num += 1
|
||||
|
||||
# Sort final images for gallery
|
||||
image_paths = sorted(image_paths)
|
||||
|
||||
end_time = time.time()
|
||||
print(f"Files copied to {target_dir_images}; took {end_time - start_time:.3f} seconds")
|
||||
return target_dir, image_paths
|
||||
|
||||
|
||||
# -------------------------------------------------------------------------
|
||||
# 3) Update gallery on upload
|
||||
# -------------------------------------------------------------------------
|
||||
def update_gallery_on_upload(input_video, input_images):
|
||||
"""
|
||||
Whenever user uploads or changes files, immediately handle them
|
||||
and show in the gallery. Return (target_dir, image_paths).
|
||||
If nothing is uploaded, returns "None" and empty list.
|
||||
"""
|
||||
if not input_video and not input_images:
|
||||
return None, None, None, None
|
||||
target_dir, image_paths = handle_uploads(input_video, input_images)
|
||||
return None, target_dir, image_paths, "Upload complete. Click 'Reconstruct' to begin 3D processing."
|
||||
|
||||
|
||||
# -------------------------------------------------------------------------
|
||||
# 4) Reconstruction: uses the target_dir plus any viz parameters
|
||||
# -------------------------------------------------------------------------
|
||||
def gradio_demo(
|
||||
target_dir,
|
||||
conf_thres=3.0,
|
||||
frame_filter="All",
|
||||
mask_black_bg=False,
|
||||
mask_white_bg=False,
|
||||
show_cam=True,
|
||||
mask_sky=False,
|
||||
prediction_mode="Pointmap Regression",
|
||||
):
|
||||
"""
|
||||
Perform reconstruction using the already-created target_dir/images.
|
||||
"""
|
||||
if not os.path.isdir(target_dir) or target_dir == "None":
|
||||
return None, "No valid target directory found. Please upload first.", None, None
|
||||
|
||||
start_time = time.time()
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
# Prepare frame_filter dropdown
|
||||
target_dir_images = os.path.join(target_dir, "images")
|
||||
all_files = sorted(os.listdir(target_dir_images)) if os.path.isdir(target_dir_images) else []
|
||||
all_files = [f"{i}: {filename}" for i, filename in enumerate(all_files)]
|
||||
frame_filter_choices = ["All"] + all_files
|
||||
|
||||
print("Running run_model...")
|
||||
with torch.no_grad():
|
||||
predictions = run_model(target_dir, model)
|
||||
|
||||
# Save predictions
|
||||
prediction_save_path = os.path.join(target_dir, "predictions.npz")
|
||||
np.savez(prediction_save_path, **predictions)
|
||||
|
||||
# Handle None frame_filter
|
||||
if frame_filter is None:
|
||||
frame_filter = "All"
|
||||
|
||||
# Build a GLB file name
|
||||
glbfile = os.path.join(
|
||||
target_dir,
|
||||
f"glbscene_{conf_thres}_{frame_filter.replace('.', '_').replace(':', '').replace(' ', '_')}_maskb{mask_black_bg}_maskw{mask_white_bg}_cam{show_cam}_sky{mask_sky}_pred{prediction_mode.replace(' ', '_')}.glb",
|
||||
)
|
||||
|
||||
# Convert predictions to GLB
|
||||
glbscene = predictions_to_glb(
|
||||
predictions,
|
||||
conf_thres=conf_thres,
|
||||
filter_by_frames=frame_filter,
|
||||
mask_black_bg=mask_black_bg,
|
||||
mask_white_bg=mask_white_bg,
|
||||
show_cam=show_cam,
|
||||
mask_sky=mask_sky,
|
||||
target_dir=target_dir,
|
||||
prediction_mode=prediction_mode,
|
||||
)
|
||||
glbscene.export(file_obj=glbfile)
|
||||
|
||||
# Cleanup
|
||||
del predictions
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
end_time = time.time()
|
||||
print(f"Total time: {end_time - start_time:.2f} seconds (including IO)")
|
||||
log_msg = f"Reconstruction Success ({len(all_files)} frames). Waiting for visualization."
|
||||
|
||||
return glbfile, log_msg, gr.Dropdown(choices=frame_filter_choices, value=frame_filter, interactive=True)
|
||||
|
||||
|
||||
# -------------------------------------------------------------------------
|
||||
# 5) Helper functions for UI resets + re-visualization
|
||||
# -------------------------------------------------------------------------
|
||||
def clear_fields():
|
||||
"""
|
||||
Clears the 3D viewer, the stored target_dir, and empties the gallery.
|
||||
"""
|
||||
return None
|
||||
|
||||
|
||||
def update_log():
|
||||
"""
|
||||
Display a quick log message while waiting.
|
||||
"""
|
||||
return "Loading and Reconstructing..."
|
||||
|
||||
|
||||
def update_visualization(
|
||||
target_dir, conf_thres, frame_filter, mask_black_bg, mask_white_bg, show_cam, mask_sky, prediction_mode, is_example
|
||||
):
|
||||
"""
|
||||
Reload saved predictions from npz, create (or reuse) the GLB for new parameters,
|
||||
and return it for the 3D viewer. If is_example == "True", skip.
|
||||
"""
|
||||
|
||||
# If it's an example click, skip as requested
|
||||
if is_example == "True":
|
||||
return None, "No reconstruction available. Please click the Reconstruct button first."
|
||||
|
||||
if not target_dir or target_dir == "None" or not os.path.isdir(target_dir):
|
||||
return None, "No reconstruction available. Please click the Reconstruct button first."
|
||||
|
||||
predictions_path = os.path.join(target_dir, "predictions.npz")
|
||||
if not os.path.exists(predictions_path):
|
||||
return None, f"No reconstruction available at {predictions_path}. Please run 'Reconstruct' first."
|
||||
|
||||
key_list = [
|
||||
"pose_enc",
|
||||
"depth",
|
||||
"depth_conf",
|
||||
"world_points",
|
||||
"world_points_conf",
|
||||
"images",
|
||||
"extrinsic",
|
||||
"intrinsic",
|
||||
"world_points_from_depth",
|
||||
]
|
||||
|
||||
loaded = np.load(predictions_path)
|
||||
predictions = {key: np.array(loaded[key]) for key in key_list}
|
||||
|
||||
glbfile = os.path.join(
|
||||
target_dir,
|
||||
f"glbscene_{conf_thres}_{frame_filter.replace('.', '_').replace(':', '').replace(' ', '_')}_maskb{mask_black_bg}_maskw{mask_white_bg}_cam{show_cam}_sky{mask_sky}_pred{prediction_mode.replace(' ', '_')}.glb",
|
||||
)
|
||||
|
||||
if not os.path.exists(glbfile):
|
||||
glbscene = predictions_to_glb(
|
||||
predictions,
|
||||
conf_thres=conf_thres,
|
||||
filter_by_frames=frame_filter,
|
||||
mask_black_bg=mask_black_bg,
|
||||
mask_white_bg=mask_white_bg,
|
||||
show_cam=show_cam,
|
||||
mask_sky=mask_sky,
|
||||
target_dir=target_dir,
|
||||
prediction_mode=prediction_mode,
|
||||
)
|
||||
glbscene.export(file_obj=glbfile)
|
||||
|
||||
return glbfile, "Updating Visualization"
|
||||
|
||||
|
||||
# -------------------------------------------------------------------------
|
||||
# Example images
|
||||
# -------------------------------------------------------------------------
|
||||
|
||||
great_wall_video = "examples/videos/great_wall.mp4"
|
||||
colosseum_video = "examples/videos/Colosseum.mp4"
|
||||
room_video = "examples/videos/room.mp4"
|
||||
kitchen_video = "examples/videos/kitchen.mp4"
|
||||
fern_video = "examples/videos/fern.mp4"
|
||||
single_cartoon_video = "examples/videos/single_cartoon.mp4"
|
||||
single_oil_painting_video = "examples/videos/single_oil_painting.mp4"
|
||||
pyramid_video = "examples/videos/pyramid.mp4"
|
||||
|
||||
|
||||
# -------------------------------------------------------------------------
|
||||
# 6) Build Gradio UI
|
||||
# -------------------------------------------------------------------------
|
||||
theme = gr.themes.Ocean()
|
||||
theme.set(
|
||||
checkbox_label_background_fill_selected="*button_primary_background_fill",
|
||||
checkbox_label_text_color_selected="*button_primary_text_color",
|
||||
)
|
||||
|
||||
with gr.Blocks(
|
||||
theme=theme,
|
||||
css="""
|
||||
.custom-log * {
|
||||
font-style: italic;
|
||||
font-size: 22px !important;
|
||||
background-image: linear-gradient(120deg, #0ea5e9 0%, #6ee7b7 60%, #34d399 100%);
|
||||
-webkit-background-clip: text;
|
||||
background-clip: text;
|
||||
font-weight: bold !important;
|
||||
color: transparent !important;
|
||||
text-align: center !important;
|
||||
}
|
||||
|
||||
.example-log * {
|
||||
font-style: italic;
|
||||
font-size: 16px !important;
|
||||
background-image: linear-gradient(120deg, #0ea5e9 0%, #6ee7b7 60%, #34d399 100%);
|
||||
-webkit-background-clip: text;
|
||||
background-clip: text;
|
||||
color: transparent !important;
|
||||
}
|
||||
|
||||
#my_radio .wrap {
|
||||
display: flex;
|
||||
flex-wrap: nowrap;
|
||||
justify-content: center;
|
||||
align-items: center;
|
||||
}
|
||||
|
||||
#my_radio .wrap label {
|
||||
display: flex;
|
||||
width: 50%;
|
||||
justify-content: center;
|
||||
align-items: center;
|
||||
margin: 0;
|
||||
padding: 10px 0;
|
||||
box-sizing: border-box;
|
||||
}
|
||||
""",
|
||||
) as demo:
|
||||
# Instead of gr.State, we use a hidden Textbox:
|
||||
is_example = gr.Textbox(label="is_example", visible=False, value="None")
|
||||
num_images = gr.Textbox(label="num_images", visible=False, value="None")
|
||||
|
||||
gr.HTML(
|
||||
"""
|
||||
<h1>🏛️ VGGT: Visual Geometry Grounded Transformer</h1>
|
||||
<p>
|
||||
<a href="https://github.com/facebookresearch/vggt">🐙 GitHub Repository</a> |
|
||||
<a href="#">Project Page</a>
|
||||
</p>
|
||||
|
||||
<div style="font-size: 16px; line-height: 1.5;">
|
||||
<p>Upload a video or a set of images to create a 3D reconstruction of a scene or object. VGGT takes these images and generates a 3D point cloud, along with estimated camera poses.</p>
|
||||
|
||||
<h3>Getting Started:</h3>
|
||||
<ol>
|
||||
<li><strong>Upload Your Data:</strong> Use the "Upload Video" or "Upload Images" buttons on the left to provide your input. Videos will be automatically split into individual frames (one frame per second).</li>
|
||||
<li><strong>Preview:</strong> Your uploaded images will appear in the gallery on the left.</li>
|
||||
<li><strong>Reconstruct:</strong> Click the "Reconstruct" button to start the 3D reconstruction process.</li>
|
||||
<li><strong>Visualize:</strong> The 3D reconstruction will appear in the viewer on the right. You can rotate, pan, and zoom to explore the model, and download the GLB file. Note the visualization of 3D points may be slow for a large number of input images.</li>
|
||||
<li>
|
||||
<strong>Adjust Visualization (Optional):</strong>
|
||||
After reconstruction, you can fine-tune the visualization using the options below
|
||||
<details style="display:inline;">
|
||||
<summary style="display:inline;">(<strong>click to expand</strong>):</summary>
|
||||
<ul>
|
||||
<li><em>Confidence Threshold:</em> Adjust the filtering of points based on confidence.</li>
|
||||
<li><em>Show Points from Frame:</em> Select specific frames to display in the point cloud.</li>
|
||||
<li><em>Show Camera:</em> Toggle the display of estimated camera positions.</li>
|
||||
<li><em>Filter Sky / Filter Black Background:</em> Remove sky or black-background points.</li>
|
||||
<li><em>Select a Prediction Mode:</em> Choose between "Depthmap and Camera Branch" or "Pointmap Branch."</li>
|
||||
</ul>
|
||||
</details>
|
||||
</li>
|
||||
</ol>
|
||||
<p><strong style="color: #0ea5e9;">Please note:</strong> <span style="color: #0ea5e9; font-weight: bold;">VGGT typically reconstructs a scene in less than 1 second. However, visualizing 3D points may take tens of seconds due to third-party rendering, which are independent of VGGT's processing time. </span></p>
|
||||
</div>
|
||||
"""
|
||||
)
|
||||
|
||||
target_dir_output = gr.Textbox(label="Target Dir", visible=False, value="None")
|
||||
|
||||
with gr.Row():
|
||||
with gr.Column(scale=2):
|
||||
input_video = gr.Video(label="Upload Video", interactive=True)
|
||||
input_images = gr.File(file_count="multiple", label="Upload Images", interactive=True)
|
||||
|
||||
image_gallery = gr.Gallery(
|
||||
label="Preview",
|
||||
columns=4,
|
||||
height="300px",
|
||||
show_download_button=True,
|
||||
object_fit="contain",
|
||||
preview=True,
|
||||
)
|
||||
|
||||
with gr.Column(scale=4):
|
||||
with gr.Column():
|
||||
gr.Markdown("**3D Reconstruction (Point Cloud and Camera Poses)**")
|
||||
log_output = gr.Markdown(
|
||||
"Please upload a video or images, then click Reconstruct.", elem_classes=["custom-log"]
|
||||
)
|
||||
reconstruction_output = gr.Model3D(height=520, zoom_speed=0.5, pan_speed=0.5)
|
||||
|
||||
with gr.Row():
|
||||
submit_btn = gr.Button("Reconstruct", scale=1, variant="primary")
|
||||
clear_btn = gr.ClearButton(
|
||||
[input_video, input_images, reconstruction_output, log_output, target_dir_output, image_gallery],
|
||||
scale=1,
|
||||
)
|
||||
|
||||
with gr.Row():
|
||||
prediction_mode = gr.Radio(
|
||||
["Depthmap and Camera Branch", "Pointmap Branch"],
|
||||
label="Select a Prediction Mode",
|
||||
value="Depthmap and Camera Branch",
|
||||
scale=1,
|
||||
elem_id="my_radio",
|
||||
)
|
||||
|
||||
with gr.Row():
|
||||
conf_thres = gr.Slider(minimum=0, maximum=100, value=50, step=0.1, label="Confidence Threshold (%)")
|
||||
frame_filter = gr.Dropdown(choices=["All"], value="All", label="Show Points from Frame")
|
||||
with gr.Column():
|
||||
show_cam = gr.Checkbox(label="Show Camera", value=True)
|
||||
mask_sky = gr.Checkbox(label="Filter Sky", value=False)
|
||||
mask_black_bg = gr.Checkbox(label="Filter Black Background", value=False)
|
||||
mask_white_bg = gr.Checkbox(label="Filter White Background", value=False)
|
||||
|
||||
# ---------------------- Examples section ----------------------
|
||||
examples = [
|
||||
[colosseum_video, "22", None, 20.0, False, False, True, False, "Depthmap and Camera Branch", "True"],
|
||||
[pyramid_video, "30", None, 35.0, False, False, True, False, "Depthmap and Camera Branch", "True"],
|
||||
[single_cartoon_video, "1", None, 15.0, False, False, True, False, "Depthmap and Camera Branch", "True"],
|
||||
[single_oil_painting_video, "1", None, 20.0, False, False, True, True, "Depthmap and Camera Branch", "True"],
|
||||
[room_video, "8", None, 5.0, False, False, True, False, "Depthmap and Camera Branch", "True"],
|
||||
[kitchen_video, "25", None, 50.0, False, False, True, False, "Depthmap and Camera Branch", "True"],
|
||||
[fern_video, "20", None, 45.0, False, False, True, False, "Depthmap and Camera Branch", "True"],
|
||||
]
|
||||
|
||||
def example_pipeline(
|
||||
input_video,
|
||||
num_images_str,
|
||||
input_images,
|
||||
conf_thres,
|
||||
mask_black_bg,
|
||||
mask_white_bg,
|
||||
show_cam,
|
||||
mask_sky,
|
||||
prediction_mode,
|
||||
is_example_str,
|
||||
):
|
||||
"""
|
||||
1) Copy example images to new target_dir
|
||||
2) Reconstruct
|
||||
3) Return model3D + logs + new_dir + updated dropdown + gallery
|
||||
We do NOT return is_example. It's just an input.
|
||||
"""
|
||||
target_dir, image_paths = handle_uploads(input_video, input_images)
|
||||
# Always use "All" for frame_filter in examples
|
||||
frame_filter = "All"
|
||||
glbfile, log_msg, dropdown = gradio_demo(
|
||||
target_dir, conf_thres, frame_filter, mask_black_bg, mask_white_bg, show_cam, mask_sky, prediction_mode
|
||||
)
|
||||
return glbfile, log_msg, target_dir, dropdown, image_paths
|
||||
|
||||
gr.Markdown("Click any row to load an example.", elem_classes=["example-log"])
|
||||
|
||||
gr.Examples(
|
||||
examples=examples,
|
||||
inputs=[
|
||||
input_video,
|
||||
num_images,
|
||||
input_images,
|
||||
conf_thres,
|
||||
mask_black_bg,
|
||||
mask_white_bg,
|
||||
show_cam,
|
||||
mask_sky,
|
||||
prediction_mode,
|
||||
is_example,
|
||||
],
|
||||
outputs=[reconstruction_output, log_output, target_dir_output, frame_filter, image_gallery],
|
||||
fn=example_pipeline,
|
||||
cache_examples=False,
|
||||
examples_per_page=50,
|
||||
)
|
||||
|
||||
# -------------------------------------------------------------------------
|
||||
# "Reconstruct" button logic:
|
||||
# - Clear fields
|
||||
# - Update log
|
||||
# - gradio_demo(...) with the existing target_dir
|
||||
# - Then set is_example = "False"
|
||||
# -------------------------------------------------------------------------
|
||||
submit_btn.click(fn=clear_fields, inputs=[], outputs=[reconstruction_output]).then(
|
||||
fn=update_log, inputs=[], outputs=[log_output]
|
||||
).then(
|
||||
fn=gradio_demo,
|
||||
inputs=[
|
||||
target_dir_output,
|
||||
conf_thres,
|
||||
frame_filter,
|
||||
mask_black_bg,
|
||||
mask_white_bg,
|
||||
show_cam,
|
||||
mask_sky,
|
||||
prediction_mode,
|
||||
],
|
||||
outputs=[reconstruction_output, log_output, frame_filter],
|
||||
).then(
|
||||
fn=lambda: "False", inputs=[], outputs=[is_example] # set is_example to "False"
|
||||
)
|
||||
|
||||
# -------------------------------------------------------------------------
|
||||
# Real-time Visualization Updates
|
||||
# -------------------------------------------------------------------------
|
||||
conf_thres.change(
|
||||
update_visualization,
|
||||
[
|
||||
target_dir_output,
|
||||
conf_thres,
|
||||
frame_filter,
|
||||
mask_black_bg,
|
||||
mask_white_bg,
|
||||
show_cam,
|
||||
mask_sky,
|
||||
prediction_mode,
|
||||
is_example,
|
||||
],
|
||||
[reconstruction_output, log_output],
|
||||
)
|
||||
frame_filter.change(
|
||||
update_visualization,
|
||||
[
|
||||
target_dir_output,
|
||||
conf_thres,
|
||||
frame_filter,
|
||||
mask_black_bg,
|
||||
mask_white_bg,
|
||||
show_cam,
|
||||
mask_sky,
|
||||
prediction_mode,
|
||||
is_example,
|
||||
],
|
||||
[reconstruction_output, log_output],
|
||||
)
|
||||
mask_black_bg.change(
|
||||
update_visualization,
|
||||
[
|
||||
target_dir_output,
|
||||
conf_thres,
|
||||
frame_filter,
|
||||
mask_black_bg,
|
||||
mask_white_bg,
|
||||
show_cam,
|
||||
mask_sky,
|
||||
prediction_mode,
|
||||
is_example,
|
||||
],
|
||||
[reconstruction_output, log_output],
|
||||
)
|
||||
mask_white_bg.change(
|
||||
update_visualization,
|
||||
[
|
||||
target_dir_output,
|
||||
conf_thres,
|
||||
frame_filter,
|
||||
mask_black_bg,
|
||||
mask_white_bg,
|
||||
show_cam,
|
||||
mask_sky,
|
||||
prediction_mode,
|
||||
is_example,
|
||||
],
|
||||
[reconstruction_output, log_output],
|
||||
)
|
||||
show_cam.change(
|
||||
update_visualization,
|
||||
[
|
||||
target_dir_output,
|
||||
conf_thres,
|
||||
frame_filter,
|
||||
mask_black_bg,
|
||||
mask_white_bg,
|
||||
show_cam,
|
||||
mask_sky,
|
||||
prediction_mode,
|
||||
is_example,
|
||||
],
|
||||
[reconstruction_output, log_output],
|
||||
)
|
||||
mask_sky.change(
|
||||
update_visualization,
|
||||
[
|
||||
target_dir_output,
|
||||
conf_thres,
|
||||
frame_filter,
|
||||
mask_black_bg,
|
||||
mask_white_bg,
|
||||
show_cam,
|
||||
mask_sky,
|
||||
prediction_mode,
|
||||
is_example,
|
||||
],
|
||||
[reconstruction_output, log_output],
|
||||
)
|
||||
prediction_mode.change(
|
||||
update_visualization,
|
||||
[
|
||||
target_dir_output,
|
||||
conf_thres,
|
||||
frame_filter,
|
||||
mask_black_bg,
|
||||
mask_white_bg,
|
||||
show_cam,
|
||||
mask_sky,
|
||||
prediction_mode,
|
||||
is_example,
|
||||
],
|
||||
[reconstruction_output, log_output],
|
||||
)
|
||||
|
||||
# -------------------------------------------------------------------------
|
||||
# Auto-update gallery whenever user uploads or changes their files
|
||||
# -------------------------------------------------------------------------
|
||||
input_video.change(
|
||||
fn=update_gallery_on_upload,
|
||||
inputs=[input_video, input_images],
|
||||
outputs=[reconstruction_output, target_dir_output, image_gallery, log_output],
|
||||
)
|
||||
input_images.change(
|
||||
fn=update_gallery_on_upload,
|
||||
inputs=[input_video, input_images],
|
||||
outputs=[reconstruction_output, target_dir_output, image_gallery, log_output],
|
||||
)
|
||||
|
||||
demo.queue(max_size=20).launch(show_error=True, share=True)
|
||||
@@ -1,402 +0,0 @@
|
||||
# Copyright (c) Meta Platforms, Inc. and affiliates.
|
||||
# All rights reserved.
|
||||
#
|
||||
# This source code is licensed under the license found in the
|
||||
# LICENSE file in the root directory of this source tree.
|
||||
|
||||
import os
|
||||
import glob
|
||||
import time
|
||||
import threading
|
||||
import argparse
|
||||
from typing import List, Optional
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from tqdm.auto import tqdm
|
||||
import viser
|
||||
import viser.transforms as viser_tf
|
||||
import cv2
|
||||
|
||||
|
||||
try:
|
||||
import onnxruntime
|
||||
except ImportError:
|
||||
print("onnxruntime not found. Sky segmentation may not work.")
|
||||
|
||||
from visual_util import segment_sky, download_file_from_url
|
||||
from vggt.models.vggt import VGGT
|
||||
from vggt.utils.load_fn import load_and_preprocess_images
|
||||
from vggt.utils.geometry import closed_form_inverse_se3, unproject_depth_map_to_point_map
|
||||
from vggt.utils.pose_enc import pose_encoding_to_extri_intri
|
||||
|
||||
|
||||
def viser_wrapper(
|
||||
pred_dict: dict,
|
||||
port: int = 8080,
|
||||
init_conf_threshold: float = 50.0, # represents percentage (e.g., 50 means filter lowest 50%)
|
||||
use_point_map: bool = False,
|
||||
background_mode: bool = False,
|
||||
mask_sky: bool = False,
|
||||
image_folder: str = None,
|
||||
):
|
||||
"""
|
||||
Visualize predicted 3D points and camera poses with viser.
|
||||
|
||||
Args:
|
||||
pred_dict (dict):
|
||||
{
|
||||
"images": (S, 3, H, W) - Input images,
|
||||
"world_points": (S, H, W, 3),
|
||||
"world_points_conf": (S, H, W),
|
||||
"depth": (S, H, W, 1),
|
||||
"depth_conf": (S, H, W),
|
||||
"extrinsic": (S, 3, 4),
|
||||
"intrinsic": (S, 3, 3),
|
||||
}
|
||||
port (int): Port number for the viser server.
|
||||
init_conf_threshold (float): Initial percentage of low-confidence points to filter out.
|
||||
use_point_map (bool): Whether to visualize world_points or use depth-based points.
|
||||
background_mode (bool): Whether to run the server in background thread.
|
||||
mask_sky (bool): Whether to apply sky segmentation to filter out sky points.
|
||||
image_folder (str): Path to the folder containing input images.
|
||||
"""
|
||||
print(f"Starting viser server on port {port}")
|
||||
|
||||
server = viser.ViserServer(host="0.0.0.0", port=port)
|
||||
server.gui.configure_theme(titlebar_content=None, control_layout="collapsible")
|
||||
|
||||
# Unpack prediction dict
|
||||
images = pred_dict["images"] # (S, 3, H, W)
|
||||
world_points_map = pred_dict["world_points"] # (S, H, W, 3)
|
||||
conf_map = pred_dict["world_points_conf"] # (S, H, W)
|
||||
|
||||
depth_map = pred_dict["depth"] # (S, H, W, 1)
|
||||
depth_conf = pred_dict["depth_conf"] # (S, H, W)
|
||||
|
||||
extrinsics_cam = pred_dict["extrinsic"] # (S, 3, 4)
|
||||
intrinsics_cam = pred_dict["intrinsic"] # (S, 3, 3)
|
||||
|
||||
# Compute world points from depth if not using the precomputed point map
|
||||
if not use_point_map:
|
||||
world_points = unproject_depth_map_to_point_map(depth_map, extrinsics_cam, intrinsics_cam)
|
||||
conf = depth_conf
|
||||
else:
|
||||
world_points = world_points_map
|
||||
conf = conf_map
|
||||
|
||||
# Apply sky segmentation if enabled
|
||||
if mask_sky and image_folder is not None:
|
||||
conf = apply_sky_segmentation(conf, image_folder)
|
||||
|
||||
# Convert images from (S, 3, H, W) to (S, H, W, 3)
|
||||
# Then flatten everything for the point cloud
|
||||
colors = images.transpose(0, 2, 3, 1) # now (S, H, W, 3)
|
||||
S, H, W, _ = world_points.shape
|
||||
|
||||
# Flatten
|
||||
points = world_points.reshape(-1, 3)
|
||||
colors_flat = (colors.reshape(-1, 3) * 255).astype(np.uint8)
|
||||
conf_flat = conf.reshape(-1)
|
||||
|
||||
cam_to_world_mat = closed_form_inverse_se3(extrinsics_cam) # shape (S, 4, 4) typically
|
||||
# For convenience, we store only (3,4) portion
|
||||
cam_to_world = cam_to_world_mat[:, :3, :]
|
||||
|
||||
# Compute scene center and recenter
|
||||
scene_center = np.mean(points, axis=0)
|
||||
points_centered = points - scene_center
|
||||
cam_to_world[..., -1] -= scene_center
|
||||
|
||||
# Store frame indices so we can filter by frame
|
||||
frame_indices = np.repeat(np.arange(S), H * W)
|
||||
|
||||
# Build the viser GUI
|
||||
gui_show_frames = server.gui.add_checkbox("Show Cameras", initial_value=True)
|
||||
|
||||
# Now the slider represents percentage of points to filter out
|
||||
gui_points_conf = server.gui.add_slider(
|
||||
"Confidence Percent", min=0, max=100, step=0.1, initial_value=init_conf_threshold
|
||||
)
|
||||
|
||||
gui_frame_selector = server.gui.add_dropdown(
|
||||
"Show Points from Frames", options=["All"] + [str(i) for i in range(S)], initial_value="All"
|
||||
)
|
||||
|
||||
# Create the main point cloud handle
|
||||
# Compute the threshold value as the given percentile
|
||||
init_threshold_val = np.percentile(conf_flat, init_conf_threshold)
|
||||
init_conf_mask = (conf_flat >= init_threshold_val) & (conf_flat > 0.1)
|
||||
point_cloud = server.scene.add_point_cloud(
|
||||
name="viser_pcd",
|
||||
points=points_centered[init_conf_mask],
|
||||
colors=colors_flat[init_conf_mask],
|
||||
point_size=0.001,
|
||||
point_shape="circle",
|
||||
)
|
||||
|
||||
# We will store references to frames & frustums so we can toggle visibility
|
||||
frames: List[viser.FrameHandle] = []
|
||||
frustums: List[viser.CameraFrustumHandle] = []
|
||||
|
||||
def visualize_frames(extrinsics: np.ndarray, images_: np.ndarray) -> None:
|
||||
"""
|
||||
Add camera frames and frustums to the scene.
|
||||
extrinsics: (S, 3, 4)
|
||||
images_: (S, 3, H, W)
|
||||
"""
|
||||
# Clear any existing frames or frustums
|
||||
for f in frames:
|
||||
f.remove()
|
||||
frames.clear()
|
||||
for fr in frustums:
|
||||
fr.remove()
|
||||
frustums.clear()
|
||||
|
||||
# Optionally attach a callback that sets the viewpoint to the chosen camera
|
||||
def attach_callback(frustum: viser.CameraFrustumHandle, frame: viser.FrameHandle) -> None:
|
||||
@frustum.on_click
|
||||
def _(_) -> None:
|
||||
for client in server.get_clients().values():
|
||||
client.camera.wxyz = frame.wxyz
|
||||
client.camera.position = frame.position
|
||||
|
||||
img_ids = range(S)
|
||||
for img_id in tqdm(img_ids):
|
||||
cam2world_3x4 = extrinsics[img_id]
|
||||
T_world_camera = viser_tf.SE3.from_matrix(cam2world_3x4)
|
||||
|
||||
# Add a small frame axis
|
||||
frame_axis = server.scene.add_frame(
|
||||
f"frame_{img_id}",
|
||||
wxyz=T_world_camera.rotation().wxyz,
|
||||
position=T_world_camera.translation(),
|
||||
axes_length=0.05,
|
||||
axes_radius=0.002,
|
||||
origin_radius=0.002,
|
||||
)
|
||||
frames.append(frame_axis)
|
||||
|
||||
# Convert the image for the frustum
|
||||
img = images_[img_id] # shape (3, H, W)
|
||||
img = (img.transpose(1, 2, 0) * 255).astype(np.uint8)
|
||||
h, w = img.shape[:2]
|
||||
|
||||
# If you want correct FOV from intrinsics, do something like:
|
||||
# fx = intrinsics_cam[img_id, 0, 0]
|
||||
# fov = 2 * np.arctan2(h/2, fx)
|
||||
# For demonstration, we pick a simple approximate FOV:
|
||||
fy = 1.1 * h
|
||||
fov = 2 * np.arctan2(h / 2, fy)
|
||||
|
||||
# Add the frustum
|
||||
frustum_cam = server.scene.add_camera_frustum(
|
||||
f"frame_{img_id}/frustum", fov=fov, aspect=w / h, scale=0.05, image=img, line_width=1.0
|
||||
)
|
||||
frustums.append(frustum_cam)
|
||||
attach_callback(frustum_cam, frame_axis)
|
||||
|
||||
def update_point_cloud() -> None:
|
||||
"""Update the point cloud based on current GUI selections."""
|
||||
# Here we compute the threshold value based on the current percentage
|
||||
current_percentage = gui_points_conf.value
|
||||
threshold_val = np.percentile(conf_flat, current_percentage)
|
||||
|
||||
print(f"Threshold absolute value: {threshold_val}, percentage: {current_percentage}%")
|
||||
|
||||
conf_mask = (conf_flat >= threshold_val) & (conf_flat > 1e-5)
|
||||
|
||||
if gui_frame_selector.value == "All":
|
||||
frame_mask = np.ones_like(conf_mask, dtype=bool)
|
||||
else:
|
||||
selected_idx = int(gui_frame_selector.value)
|
||||
frame_mask = frame_indices == selected_idx
|
||||
|
||||
combined_mask = conf_mask & frame_mask
|
||||
point_cloud.points = points_centered[combined_mask]
|
||||
point_cloud.colors = colors_flat[combined_mask]
|
||||
|
||||
@gui_points_conf.on_update
|
||||
def _(_) -> None:
|
||||
update_point_cloud()
|
||||
|
||||
@gui_frame_selector.on_update
|
||||
def _(_) -> None:
|
||||
update_point_cloud()
|
||||
|
||||
@gui_show_frames.on_update
|
||||
def _(_) -> None:
|
||||
"""Toggle visibility of camera frames and frustums."""
|
||||
for f in frames:
|
||||
f.visible = gui_show_frames.value
|
||||
for fr in frustums:
|
||||
fr.visible = gui_show_frames.value
|
||||
|
||||
# Add the camera frames to the scene
|
||||
visualize_frames(cam_to_world, images)
|
||||
|
||||
print("Starting viser server...")
|
||||
# If background_mode is True, spawn a daemon thread so the main thread can continue.
|
||||
if background_mode:
|
||||
|
||||
def server_loop():
|
||||
while True:
|
||||
time.sleep(0.001)
|
||||
|
||||
thread = threading.Thread(target=server_loop, daemon=True)
|
||||
thread.start()
|
||||
else:
|
||||
while True:
|
||||
time.sleep(0.01)
|
||||
|
||||
return server
|
||||
|
||||
|
||||
# Helper functions for sky segmentation
|
||||
|
||||
|
||||
def apply_sky_segmentation(conf: np.ndarray, image_folder: str) -> np.ndarray:
|
||||
"""
|
||||
Apply sky segmentation to confidence scores.
|
||||
|
||||
Args:
|
||||
conf (np.ndarray): Confidence scores with shape (S, H, W)
|
||||
image_folder (str): Path to the folder containing input images
|
||||
|
||||
Returns:
|
||||
np.ndarray: Updated confidence scores with sky regions masked out
|
||||
"""
|
||||
S, H, W = conf.shape
|
||||
sky_masks_dir = image_folder.rstrip("/") + "_sky_masks"
|
||||
os.makedirs(sky_masks_dir, exist_ok=True)
|
||||
|
||||
# Download skyseg.onnx if it doesn't exist
|
||||
if not os.path.exists("skyseg.onnx"):
|
||||
print("Downloading skyseg.onnx...")
|
||||
download_file_from_url("https://huggingface.co/JianyuanWang/skyseg/resolve/main/skyseg.onnx", "skyseg.onnx")
|
||||
|
||||
skyseg_session = onnxruntime.InferenceSession("skyseg.onnx")
|
||||
image_files = sorted(glob.glob(os.path.join(image_folder, "*")))
|
||||
sky_mask_list = []
|
||||
|
||||
print("Generating sky masks...")
|
||||
for i, image_path in enumerate(tqdm(image_files[:S])): # Limit to the number of images in the batch
|
||||
image_name = os.path.basename(image_path)
|
||||
mask_filepath = os.path.join(sky_masks_dir, image_name)
|
||||
|
||||
if os.path.exists(mask_filepath):
|
||||
sky_mask = cv2.imread(mask_filepath, cv2.IMREAD_GRAYSCALE)
|
||||
else:
|
||||
sky_mask = segment_sky(image_path, skyseg_session, mask_filepath)
|
||||
|
||||
# Resize mask to match H×W if needed
|
||||
if sky_mask.shape[0] != H or sky_mask.shape[1] != W:
|
||||
sky_mask = cv2.resize(sky_mask, (W, H))
|
||||
|
||||
sky_mask_list.append(sky_mask)
|
||||
|
||||
# Convert list to numpy array with shape S×H×W
|
||||
sky_mask_array = np.array(sky_mask_list)
|
||||
# Apply sky mask to confidence scores
|
||||
sky_mask_binary = (sky_mask_array > 0.1).astype(np.float32)
|
||||
conf = conf * sky_mask_binary
|
||||
|
||||
print("Sky segmentation applied successfully")
|
||||
return conf
|
||||
|
||||
|
||||
parser = argparse.ArgumentParser(description="VGGT demo with viser for 3D visualization")
|
||||
parser.add_argument(
|
||||
"--image_folder", type=str, default="examples/kitchen/images/", help="Path to folder containing images"
|
||||
)
|
||||
parser.add_argument("--use_point_map", action="store_true", help="Use point map instead of depth-based points")
|
||||
parser.add_argument("--background_mode", action="store_true", help="Run the viser server in background mode")
|
||||
parser.add_argument("--port", type=int, default=8080, help="Port number for the viser server")
|
||||
parser.add_argument(
|
||||
"--conf_threshold", type=float, default=25.0, help="Initial percentage of low-confidence points to filter out"
|
||||
)
|
||||
parser.add_argument("--mask_sky", action="store_true", help="Apply sky segmentation to filter out sky points")
|
||||
|
||||
|
||||
def main():
|
||||
"""
|
||||
Main function for the VGGT demo with viser for 3D visualization.
|
||||
|
||||
This function:
|
||||
1. Loads the VGGT model
|
||||
2. Processes input images from the specified folder
|
||||
3. Runs inference to generate 3D points and camera poses
|
||||
4. Optionally applies sky segmentation to filter out sky points
|
||||
5. Visualizes the results using viser
|
||||
|
||||
Command-line arguments:
|
||||
--image_folder: Path to folder containing input images
|
||||
--use_point_map: Use point map instead of depth-based points
|
||||
--background_mode: Run the viser server in background mode
|
||||
--port: Port number for the viser server
|
||||
--conf_threshold: Initial percentage of low-confidence points to filter out
|
||||
--mask_sky: Apply sky segmentation to filter out sky points
|
||||
"""
|
||||
args = parser.parse_args()
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
print(f"Using device: {device}")
|
||||
|
||||
print("Initializing and loading VGGT model...")
|
||||
# model = VGGT.from_pretrained("facebook/VGGT-1B")
|
||||
|
||||
model = VGGT()
|
||||
_URL = "https://huggingface.co/facebook/VGGT-1B/resolve/main/model.pt"
|
||||
model.load_state_dict(torch.hub.load_state_dict_from_url(_URL))
|
||||
|
||||
model.eval()
|
||||
model = model.to(device)
|
||||
|
||||
# Use the provided image folder path
|
||||
print(f"Loading images from {args.image_folder}...")
|
||||
image_names = glob.glob(os.path.join(args.image_folder, "*"))
|
||||
print(f"Found {len(image_names)} images")
|
||||
|
||||
images = load_and_preprocess_images(image_names).to(device)
|
||||
print(f"Preprocessed images shape: {images.shape}")
|
||||
|
||||
print("Running inference...")
|
||||
dtype = torch.bfloat16 if torch.cuda.get_device_capability()[0] >= 8 else torch.float16
|
||||
|
||||
with torch.no_grad():
|
||||
with torch.cuda.amp.autocast(dtype=dtype):
|
||||
predictions = model(images)
|
||||
|
||||
print("Converting pose encoding to extrinsic and intrinsic matrices...")
|
||||
extrinsic, intrinsic = pose_encoding_to_extri_intri(predictions["pose_enc"], images.shape[-2:])
|
||||
predictions["extrinsic"] = extrinsic
|
||||
predictions["intrinsic"] = intrinsic
|
||||
|
||||
print("Processing model outputs...")
|
||||
for key in predictions.keys():
|
||||
if isinstance(predictions[key], torch.Tensor):
|
||||
predictions[key] = predictions[key].cpu().numpy().squeeze(0) # remove batch dimension and convert to numpy
|
||||
|
||||
if args.use_point_map:
|
||||
print("Visualizing 3D points from point map")
|
||||
else:
|
||||
print("Visualizing 3D points by unprojecting depth map by cameras")
|
||||
|
||||
if args.mask_sky:
|
||||
print("Sky segmentation enabled - will filter out sky points")
|
||||
|
||||
print("Starting viser visualization...")
|
||||
|
||||
viser_server = viser_wrapper(
|
||||
predictions,
|
||||
port=args.port,
|
||||
init_conf_threshold=args.conf_threshold,
|
||||
use_point_map=args.use_point_map,
|
||||
background_mode=args.background_mode,
|
||||
mask_sky=args.mask_sky,
|
||||
image_folder=args.image_folder,
|
||||
)
|
||||
print("Visualization complete")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -1,45 +0,0 @@
|
||||
# Alternative Installation Methods
|
||||
|
||||
This document explains how to install VGGT as a package using different package managers.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
Before installing VGGT as a package, you need to install PyTorch and torchvision. We don't list these as dependencies to avoid CUDA version mismatches. Install them first, with an example as:
|
||||
|
||||
```bash
|
||||
# install pytorch 2.3.1 with cuda 12.1
|
||||
pip install torch==2.3.1 torchvision==0.18.1 --index-url https://download.pytorch.org/whl/cu121
|
||||
```
|
||||
|
||||
## Installation Options
|
||||
|
||||
### Install with pip
|
||||
|
||||
The simplest way to install VGGT is using pip:
|
||||
|
||||
```bash
|
||||
pip install -e .
|
||||
```
|
||||
|
||||
### Install and run with pixi
|
||||
|
||||
[Pixi](https://pixi.sh) is a package management tool for creating reproducible environments.
|
||||
|
||||
1. First, [download and install pixi](https://pixi.sh/latest/get_started/)
|
||||
2. Then run:
|
||||
|
||||
```bash
|
||||
pixi run -e python demo_gradio.py
|
||||
```
|
||||
|
||||
### Install and run with uv
|
||||
|
||||
[uv](https://docs.astral.sh/uv/) is a fast Python package installer and resolver.
|
||||
|
||||
1. First, [install uv](https://docs.astral.sh/uv/getting-started/installation/)
|
||||
2. Then run:
|
||||
|
||||
```bash
|
||||
uv run --extra demo demo_gradio.py
|
||||
```
|
||||
|
||||

|
Before Width: | Height: | Size: 675 KiB |

|
Before Width: | Height: | Size: 709 KiB |

|
Before Width: | Height: | Size: 771 KiB |

|
Before Width: | Height: | Size: 809 KiB |

|
Before Width: | Height: | Size: 707 KiB |

|
Before Width: | Height: | Size: 742 KiB |

|
Before Width: | Height: | Size: 658 KiB |

|
Before Width: | Height: | Size: 836 KiB |

|
Before Width: | Height: | Size: 661 KiB |

|
Before Width: | Height: | Size: 778 KiB |

|
Before Width: | Height: | Size: 713 KiB |

|
Before Width: | Height: | Size: 780 KiB |

|
Before Width: | Height: | Size: 690 KiB |

|
Before Width: | Height: | Size: 737 KiB |

|
Before Width: | Height: | Size: 627 KiB |

|
Before Width: | Height: | Size: 624 KiB |

|
Before Width: | Height: | Size: 737 KiB |

|
Before Width: | Height: | Size: 756 KiB |

|
Before Width: | Height: | Size: 810 KiB |

|
Before Width: | Height: | Size: 662 KiB |

|
Before Width: | Height: | Size: 701 KiB |

|
Before Width: | Height: | Size: 768 KiB |

|
Before Width: | Height: | Size: 659 KiB |

|
Before Width: | Height: | Size: 636 KiB |

|
Before Width: | Height: | Size: 781 KiB |

|
Before Width: | Height: | Size: 655 KiB |

|
Before Width: | Height: | Size: 650 KiB |

|
Before Width: | Height: | Size: 636 KiB |

|
Before Width: | Height: | Size: 638 KiB |

|
Before Width: | Height: | Size: 595 KiB |

|
Before Width: | Height: | Size: 618 KiB |

|
Before Width: | Height: | Size: 619 KiB |

|
Before Width: | Height: | Size: 618 KiB |

|
Before Width: | Height: | Size: 618 KiB |

|
Before Width: | Height: | Size: 625 KiB |

|
Before Width: | Height: | Size: 622 KiB |

|
Before Width: | Height: | Size: 604 KiB |

|
Before Width: | Height: | Size: 632 KiB |

|
Before Width: | Height: | Size: 635 KiB |

|
Before Width: | Height: | Size: 625 KiB |

|
Before Width: | Height: | Size: 617 KiB |

|
Before Width: | Height: | Size: 624 KiB |

|
Before Width: | Height: | Size: 627 KiB |

|
Before Width: | Height: | Size: 620 KiB |

|
Before Width: | Height: | Size: 630 KiB |

|
Before Width: | Height: | Size: 640 KiB |

|
Before Width: | Height: | Size: 629 KiB |

|
Before Width: | Height: | Size: 643 KiB |

|
Before Width: | Height: | Size: 633 KiB |

|
Before Width: | Height: | Size: 634 KiB |

|
Before Width: | Height: | Size: 636 KiB |

|
Before Width: | Height: | Size: 636 KiB |

|
Before Width: | Height: | Size: 631 KiB |

|
Before Width: | Height: | Size: 639 KiB |

|
Before Width: | Height: | Size: 626 KiB |

|
Before Width: | Height: | Size: 625 KiB |

|
Before Width: | Height: | Size: 627 KiB |

|
Before Width: | Height: | Size: 627 KiB |

|
Before Width: | Height: | Size: 634 KiB |

|
Before Width: | Height: | Size: 633 KiB |

|
Before Width: | Height: | Size: 629 KiB |

|
Before Width: | Height: | Size: 638 KiB |

|
Before Width: | Height: | Size: 628 KiB |

|
Before Width: | Height: | Size: 639 KiB |

|
Before Width: | Height: | Size: 622 KiB |

|
Before Width: | Height: | Size: 632 KiB |

|
Before Width: | Height: | Size: 632 KiB |

|
Before Width: | Height: | Size: 632 KiB |

|
Before Width: | Height: | Size: 628 KiB |

|
Before Width: | Height: | Size: 624 KiB |

|
Before Width: | Height: | Size: 299 KiB |

|
Before Width: | Height: | Size: 269 KiB |

|
Before Width: | Height: | Size: 243 KiB |

|
Before Width: | Height: | Size: 225 KiB |

|
Before Width: | Height: | Size: 260 KiB |

|
Before Width: | Height: | Size: 264 KiB |

|
Before Width: | Height: | Size: 255 KiB |

|
Before Width: | Height: | Size: 187 KiB |

|
Before Width: | Height: | Size: 313 KiB |

|
Before Width: | Height: | Size: 389 KiB |