add HMControlNet2
This commit is contained in:
 songkey-win
@@ -22,8 +22,12 @@
|
||||
|
||||
|
||||
## 🔆 New Features/Updates
|
||||
- ✅ `11/14/2024` Added the `HMControlNet2` module, which uses the `PD-FGC` motion module to extract facial expression information (`drive_exp2`); restructured the ComfyUI interface; and optimized VRAM usage.
|
||||
|
||||
[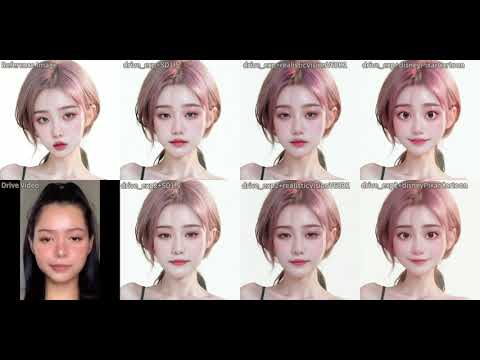](https://www.youtube.com/watch?v=ZvoMHyRm310)
|
||||
|
||||
- ✅ `11/12/2024` Added a newly fine-tuned version of [`Animatediff`](https://huggingface.co/songkey/hm_animatediff_frame12) with a patch size of 12, which uses less VRAM (Tested on 2080Ti).
|
||||
- ✅ `11/11/2024` Optimized VRAM usage and added `HMVideoSimplePipeline` (`workflows/hellomeme_video_simple_workflow.json`), which doesn’t use Animatediff and can run on machines with less than 12G VRAM.
|
||||
- ✅ `11/11/2024` ~~Optimized VRAM usage and added `HMVideoSimplePipeline` (`workflows/hellomeme_video_simple_workflow.json`), which doesn’t use Animatediff and can run on machines with less than 12G VRAM.~~
|
||||
- ✅ `11/6/2024` The face proportion in the reference image significantly affects the generation quality. We have encapsulated the **recommended image cropping method** used during training into a `CropReferenceImage` Node. Refer to the workflows in the `ComfyUI_HelloMeme/workflows directory`: `hellomeme_video_cropref_workflow.json` and `hellomeme_image_cropref_workflow.json`.
|
||||
|
||||
|
||||
@@ -41,12 +45,12 @@ This repository is the official implementation of the [`HelloMeme`](https://arxi
|
||||
### Image Generation Interface
|
||||
|
||||
<p align="center">
|
||||
<img src="workflows/hellomeme_image_example.jpg" alt="image_generation_interface">
|
||||
<img src="workflows/hellomeme_image_example.png" alt="image_generation_interface">
|
||||
</p>
|
||||
|
||||
### Video Generation Interface
|
||||
|
||||
<p align="center">
|
||||
<img src="workflows/hellomeme_video_example.jpg" alt="video_generation_interface">
|
||||
<img src="workflows/hellomeme_video_example.png" alt="video_generation_interface">
|
||||
</p>
|
||||
|
||||
|
||||
@@ -8,5 +8,5 @@
|
||||
@Desc :
|
||||
"""
|
||||
|
||||
from .pipelines import HMVideoPipeline, HMImagePipeline, HMVideoSimplePipeline
|
||||
from .pipelines import HMVideoPipeline, HMImagePipeline
|
||||
from .models import HMDenoising3D, HMDenoisingMotion, HMControlNet, HMReferenceAdapter
|
||||
@@ -9,6 +9,6 @@
|
||||
"""
|
||||
|
||||
from .hm_denoising_motion import HMDenoisingMotion
|
||||
from .hm_control import HMControlNet
|
||||
from .hm_control import HMControlNet, HMControlNet2
|
||||
from .hm_blocks import HMReferenceAdapter
|
||||
from .hm_denoising_3d import HMDenoising3D
|
||||
|
||||
@@ -85,4 +85,62 @@ class HMControlNet(ModelMixin, ConfigMixin):
|
||||
ret_dict[f'down_{idx}'] = rearrange(embedding,
|
||||
"(b f) c h w -> b c f h w",
|
||||
f=video_length)
|
||||
return ret_dict
|
||||
|
||||
class HMControlNet2(ModelMixin, ConfigMixin):
|
||||
@register_to_config
|
||||
def __init__(
|
||||
self,
|
||||
embedding_channels: int,
|
||||
input_channels: int = 3,
|
||||
scale_factor: int = 8,
|
||||
cross_attention_dim: int = 320,
|
||||
block_out_channels: Tuple[int] = (128, 320, 640, 1280),
|
||||
):
|
||||
super().__init__()
|
||||
self.scale_factor = scale_factor
|
||||
self.embedding_channels = embedding_channels
|
||||
self.cross_attention_dim = cross_attention_dim
|
||||
self.conv_in = nn.Conv2d(input_channels, block_out_channels[0], kernel_size=3, padding=1, bias=False)
|
||||
|
||||
self.exp_embedding = Timesteps(cross_attention_dim, True, 0)
|
||||
self.emo_proj = TimestepEmbedding(cross_attention_dim, cross_attention_dim)
|
||||
|
||||
self.blocks_down = nn.ModuleList([])
|
||||
for i in range(1, len(block_out_channels)):
|
||||
channel_in = block_out_channels[i-1]
|
||||
channel_out = block_out_channels[i]
|
||||
self.blocks_down.append(
|
||||
SKCrossAttention(
|
||||
channel_in=channel_in,
|
||||
channel_out=channel_out,
|
||||
cross_attention_dim=cross_attention_dim,
|
||||
num_positional_embeddings=64,
|
||||
num_positional_embeddings_hidden=1024
|
||||
)
|
||||
)
|
||||
|
||||
def forward(self, condition, emo_embedding):
|
||||
bs, _, video_length, h, w = condition.shape
|
||||
|
||||
condition = rearrange(condition, "b c f h w -> (b f) c h w")
|
||||
condition = F.interpolate(condition,
|
||||
size=(h // self.scale_factor, w // self.scale_factor),
|
||||
mode='bilinear',
|
||||
align_corners=False)
|
||||
embedding = self.conv_in(condition)
|
||||
|
||||
drive_coeff = rearrange(emo_embedding * 20., "b f c -> (b f c)")
|
||||
drive_embedding = self.exp_embedding(drive_coeff).to(dtype=embedding.dtype)
|
||||
drive_embedding = rearrange(drive_embedding, "(b f c) d -> b f c d",
|
||||
b=bs, f=video_length, d=self.cross_attention_dim)
|
||||
drive_embedding = rearrange(drive_embedding, "b f c d -> (b f) c d")
|
||||
drive_embedding = self.emo_proj(drive_embedding)
|
||||
|
||||
ret_dict = {}
|
||||
for idx, block in enumerate(self.blocks_down):
|
||||
embedding = block(embedding, drive_embedding)
|
||||
ret_dict[f'down2_{idx}'] = rearrange(embedding,
|
||||
"(b f) c h w -> b c f h w",
|
||||
f=video_length)
|
||||
return ret_dict
|
||||
@@ -191,6 +191,8 @@ class HMDenoising3D(UNet2DConditionModel, CopyWeights, InsertReferenceAdapter):
|
||||
|
||||
if not control_hidden_states is None and f'down_{idx}' in control_hidden_states:
|
||||
sample += rearrange(control_hidden_states[f'down_{idx}'], "b c f h w -> (b f) c h w")
|
||||
if not control_hidden_states is None and f'down2_{idx}' in control_hidden_states:
|
||||
sample += rearrange(control_hidden_states[f'down2_{idx}'], "b c f h w -> (b f) c h w")
|
||||
if hasattr(self, 'reference_modules_down') and not reference_hidden_states is None and f'down_{idx}' in reference_hidden_states:
|
||||
sample = self.reference_modules_down[idx](sample, reference_hidden_states[f'down_{idx}'], num_frames)
|
||||
|
||||
|
||||
@@ -143,7 +143,8 @@ class HMDenoisingMotion(UNetMotionModel, InsertReferenceAdapter):
|
||||
|
||||
if not control_hidden_states is None and f'down_{idx}' in control_hidden_states:
|
||||
sample += rearrange(control_hidden_states[f'down_{idx}'], "b c f h w -> (b f) c h w")
|
||||
|
||||
if not control_hidden_states is None and f'down2_{idx}' in control_hidden_states:
|
||||
sample += rearrange(control_hidden_states[f'down2_{idx}'], "b c f h w -> (b f) c h w")
|
||||
|
||||
if hasattr(self, 'reference_modules_down') and not reference_hidden_states is None and f'down_{idx}' in reference_hidden_states:
|
||||
sample = self.reference_modules_down[idx](sample, reference_hidden_states[f'down_{idx}'], num_frames)
|
||||
|
||||
@@ -8,6 +8,5 @@
|
||||
@Desc :
|
||||
"""
|
||||
|
||||
from .pipline_hm_video_simple import HMVideoSimplePipeline
|
||||
from .pipline_hm_image import HMImagePipeline
|
||||
from .pipline_hm_video import HMVideoPipeline
|
||||
|
||||
@@ -10,7 +10,7 @@ adapted from: https://github.com/huggingface/diffusers/blob/main/src/diffusers/p
|
||||
"""
|
||||
|
||||
from typing import Any, Callable, Dict, List, Optional, Union
|
||||
|
||||
from einops import rearrange
|
||||
import torch
|
||||
|
||||
from diffusers.callbacks import MultiPipelineCallbacks, PipelineCallback
|
||||
@@ -22,7 +22,7 @@ from diffusers.pipelines.stable_diffusion.pipeline_output import StableDiffusion
|
||||
from diffusers import StableDiffusionImg2ImgPipeline
|
||||
from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion_img2img import retrieve_timesteps, retrieve_latents
|
||||
|
||||
from ..models import HMDenoising3D, HMControlNet
|
||||
from ..models import HMDenoising3D, HMControlNet, HMControlNet2
|
||||
from ..models import HMReferenceAdapter
|
||||
|
||||
class HMImagePipeline(StableDiffusionImg2ImgPipeline):
|
||||
@@ -42,9 +42,15 @@ class HMImagePipeline(StableDiffusionImg2ImgPipeline):
|
||||
self.unet_ref = self.unet_ref.to(device=device, dtype=dtype).eval()
|
||||
self.unet = self.unet.to(device=device, dtype=dtype).eval()
|
||||
|
||||
if not hasattr(self, "mp_control"):
|
||||
self.mp_control = HMControlNet.from_pretrained('songkey/hm_control')
|
||||
self.mp_control = self.mp_control.to(device=device, dtype=dtype).eval()
|
||||
if hasattr(self, "mp_control"):
|
||||
del self.mp_control
|
||||
self.mp_control = HMControlNet.from_pretrained('songkey/hm_control')
|
||||
self.mp_control = self.mp_control.to(device=device, dtype=dtype).eval()
|
||||
|
||||
if hasattr(self, "mp_control2"):
|
||||
del self.mp_control2
|
||||
self.mp_control2 = HMControlNet2.from_pretrained('songkey/hm_control2')
|
||||
self.mp_control2 = self.mp_control2.to(device=device, dtype=dtype).eval()
|
||||
|
||||
@torch.no_grad()
|
||||
def __call__(
|
||||
@@ -171,14 +177,31 @@ class HMImagePipeline(StableDiffusionImg2ImgPipeline):
|
||||
ref_latents = self.vae.config.scaling_factor * ref_latents
|
||||
|
||||
condition = drive_params['condition'].clone().to(device=device)
|
||||
drive_coeff = drive_params['drive_coeff'].clone().to(device=device)
|
||||
face_parts = drive_params['face_parts'].clone().to(device=device)
|
||||
|
||||
if self.do_classifier_free_guidance:
|
||||
condition = torch.cat([torch.ones_like(condition) * -1, condition], dim=0)
|
||||
drive_coeff = torch.cat([torch.zeros_like(drive_coeff), drive_coeff], dim=0)
|
||||
face_parts = torch.cat([torch.zeros_like(face_parts), face_parts], dim=0)
|
||||
control_latents = self.mp_control(condition=condition, drive_coeff=drive_coeff, face_parts=face_parts)
|
||||
|
||||
control_latents = {}
|
||||
if 'drive_coeff' in drive_params:
|
||||
self.mp_control.to(device=device)
|
||||
drive_coeff = drive_params['drive_coeff'].clone().to(device=device)
|
||||
face_parts = drive_params['face_parts'].clone().to(device=device)
|
||||
if self.do_classifier_free_guidance:
|
||||
drive_coeff = torch.cat([torch.zeros_like(drive_coeff), drive_coeff], dim=0)
|
||||
face_parts = torch.cat([torch.zeros_like(face_parts), face_parts], dim=0)
|
||||
control_latents1 = self.mp_control(condition=condition, drive_coeff=drive_coeff, face_parts=face_parts)
|
||||
control_latents.update(control_latents1)
|
||||
self.mp_control.cpu()
|
||||
|
||||
if 'pd_fpg' in drive_params:
|
||||
self.mp_control2.to(device=device)
|
||||
pd_fpg = drive_params['pd_fpg'].clone().to(device=device)
|
||||
if self.do_classifier_free_guidance:
|
||||
neg_pd_fpg = drive_params['neg_pd_fpg'].clone().to(device=device)
|
||||
neg_pd_fpg.repeat_interleave(pd_fpg.size(1), dim=1)
|
||||
pd_fpg = torch.cat([neg_pd_fpg, pd_fpg], dim=0)
|
||||
control_latents2 = self.mp_control2(condition=condition, emo_embedding=pd_fpg)
|
||||
control_latents.update(control_latents2)
|
||||
self.mp_control2.cpu()
|
||||
|
||||
# 7. Prepare extra step kwargs. TODO: Logic should ideally just be moved out of the pipeline
|
||||
extra_step_kwargs = self.prepare_extra_step_kwargs(generator, eta)
|
||||
@@ -191,13 +214,14 @@ class HMImagePipeline(StableDiffusionImg2ImgPipeline):
|
||||
)
|
||||
|
||||
latent_model_input = torch.cat([torch.zeros_like(ref_latents), ref_latents]) if self.do_classifier_free_guidance else ref_latents
|
||||
self.unet_ref.to(device=device)
|
||||
cached_res = self.unet_ref(
|
||||
latent_model_input.unsqueeze(2),
|
||||
0,
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
# added_cond_kwargs=added_cond_kwargs,
|
||||
return_dict=False,
|
||||
)[1]
|
||||
self.unet_ref.cpu()
|
||||
|
||||
# 7.2 Optionally get Guidance Scale Embedding
|
||||
timestep_cond = None
|
||||
|
||||
@@ -20,7 +20,7 @@ from diffusers.utils.torch_utils import randn_tensor
|
||||
from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion_img2img import retrieve_timesteps, retrieve_latents
|
||||
from diffusers import StableDiffusionImg2ImgPipeline, MotionAdapter, EulerDiscreteScheduler
|
||||
|
||||
from ..models import HMDenoising3D, HMDenoisingMotion, HMControlNet
|
||||
from ..models import HMDenoising3D, HMDenoisingMotion, HMControlNet, HMControlNet2
|
||||
from ..models import HMReferenceAdapter
|
||||
from ..utils import dicts_to_device, cat_dicts
|
||||
|
||||
@@ -57,6 +57,11 @@ class HMVideoPipeline(StableDiffusionImg2ImgPipeline):
|
||||
self.mp_control = HMControlNet.from_pretrained('songkey/hm_control')
|
||||
self.mp_control = self.mp_control.to(device=device, dtype=dtype).eval()
|
||||
|
||||
if hasattr(self, "mp_control2"):
|
||||
del self.mp_control2
|
||||
self.mp_control2 = HMControlNet2.from_pretrained('songkey/hm_control2')
|
||||
self.mp_control2 = self.mp_control2.to(device=device, dtype=dtype).eval()
|
||||
|
||||
@torch.no_grad()
|
||||
def __call__(
|
||||
self,
|
||||
@@ -132,7 +137,7 @@ class HMVideoPipeline(StableDiffusionImg2ImgPipeline):
|
||||
else:
|
||||
batch_size = prompt_embeds.shape[0]
|
||||
|
||||
device = self._execution_device
|
||||
device = self.device
|
||||
|
||||
# 3. Encode input prompt
|
||||
text_encoder_lora_scale = (
|
||||
@@ -196,8 +201,9 @@ class HMVideoPipeline(StableDiffusionImg2ImgPipeline):
|
||||
)
|
||||
|
||||
ref_latents = ref_latents.unsqueeze(2)
|
||||
self.unet_ref.to(device=device)
|
||||
cached_res = self.unet_ref(
|
||||
torch.cat([torch.zeros_like(ref_latents), ref_latents], dim=0) if
|
||||
torch.cat([ref_latents, ref_latents], dim=0) if
|
||||
self.do_classifier_free_guidance else ref_latents,
|
||||
0,
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
@@ -214,24 +220,44 @@ class HMVideoPipeline(StableDiffusionImg2ImgPipeline):
|
||||
|
||||
pre_latents = []
|
||||
control_latents = []
|
||||
control_latent_neg = None
|
||||
control_latent1_neg, control_latent2_neg = None, None
|
||||
base_noise = randn_tensor([batch_size, c, 1, h, w], dtype=prompt_embeds.dtype, generator=generator).to(device=device)
|
||||
self.mp_control.to(device=device)
|
||||
self.mp_control2.to(device=device)
|
||||
with self.progress_bar(total=raw_video_len) as progress_bar:
|
||||
for idx in range(raw_video_len):
|
||||
condition = drive_params['condition'][:, :, idx:idx+1].clone().to(device=device)
|
||||
drive_coeff = drive_params['drive_coeff'][:, idx:idx+1].clone().to(device=device)
|
||||
face_parts = drive_params['face_parts'][:, idx:idx+1].clone().to(device=device)
|
||||
|
||||
if control_latent_neg is None and self.do_classifier_free_guidance:
|
||||
control_latent_neg = self.mp_control(condition=torch.ones_like(condition)*-1,
|
||||
drive_coeff=torch.zeros_like(drive_coeff),
|
||||
face_parts=torch.zeros_like(face_parts))
|
||||
control_latent_input = {}
|
||||
if 'drive_coeff' in drive_params:
|
||||
drive_coeff = drive_params['drive_coeff'][:, idx:idx+1].clone().to(device=device)
|
||||
face_parts = drive_params['face_parts'][:, idx:idx+1].clone().to(device=device)
|
||||
|
||||
control_latent = self.mp_control(condition=condition,
|
||||
drive_coeff=drive_coeff,
|
||||
face_parts=face_parts)
|
||||
if self.do_classifier_free_guidance:
|
||||
control_latent = cat_dicts([control_latent_neg, control_latent], dim=0)
|
||||
if control_latent1_neg is None and self.do_classifier_free_guidance:
|
||||
control_latent1_neg = self.mp_control(condition=torch.ones_like(condition)*-1,
|
||||
drive_coeff=torch.zeros_like(drive_coeff),
|
||||
face_parts=torch.zeros_like(face_parts))
|
||||
|
||||
control_latent1 = self.mp_control(condition=condition,
|
||||
drive_coeff=drive_coeff,
|
||||
face_parts=face_parts)
|
||||
if self.do_classifier_free_guidance:
|
||||
control_latent1 = cat_dicts([control_latent1_neg, control_latent1], dim=0)
|
||||
|
||||
control_latent_input.update(control_latent1)
|
||||
|
||||
if 'pd_fpg' in drive_params:
|
||||
pd_fpg = drive_params['pd_fpg'][:, idx:idx+1].clone().to(device=device)
|
||||
|
||||
if control_latent2_neg is None and self.do_classifier_free_guidance:
|
||||
control_latent2_neg = self.mp_control2(condition=torch.ones_like(condition)*-1,
|
||||
emo_embedding=drive_params['neg_pd_fpg'].clone().to(device=device))
|
||||
|
||||
control_latent2 = self.mp_control2(condition=condition, emo_embedding=pd_fpg)
|
||||
if self.do_classifier_free_guidance:
|
||||
control_latent2 = cat_dicts([control_latent2_neg, control_latent2], dim=0)
|
||||
|
||||
control_latent_input.update(control_latent2)
|
||||
|
||||
scheduler = EulerDiscreteScheduler(
|
||||
num_train_timesteps=1000,
|
||||
@@ -257,7 +283,7 @@ class HMVideoPipeline(StableDiffusionImg2ImgPipeline):
|
||||
t,
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
reference_hidden_states=cached_res,
|
||||
control_hidden_states=control_latent,
|
||||
control_hidden_states=control_latent_input,
|
||||
timestep_cond=timestep_cond,
|
||||
cross_attention_kwargs=self.cross_attention_kwargs,
|
||||
added_cond_kwargs=added_cond_kwargs,
|
||||
@@ -269,15 +295,18 @@ class HMVideoPipeline(StableDiffusionImg2ImgPipeline):
|
||||
pred_latent = scheduler.step(noise_pred_chunk, t, pred_latent,
|
||||
**extra_step_kwargs, return_dict=False)[0]
|
||||
pre_latents.append(pred_latent.cpu())
|
||||
control_latents.append(dicts_to_device([control_latent], device='cpu')[0])
|
||||
control_latents.append(dicts_to_device([control_latent_input], device='cpu')[0])
|
||||
|
||||
progress_bar.set_description(f"GEN stage1")
|
||||
progress_bar.update()
|
||||
|
||||
pre_latents = torch.cat(pre_latents, dim=2)
|
||||
self.mp_control.cpu()
|
||||
self.mp_control2.cpu()
|
||||
self.unet_ref.cpu()
|
||||
|
||||
chunk_size = self.num_frames
|
||||
chunk_overlap = min(max(0, chunk_overlap), chunk_size // 2)
|
||||
chunk_overlap = min(max(0, chunk_overlap), chunk_size // 2 - 1)
|
||||
chunk_stride = chunk_size - chunk_overlap
|
||||
|
||||
drive_idx_list = list(range(raw_video_len))
|
||||
@@ -297,21 +326,28 @@ class HMVideoPipeline(StableDiffusionImg2ImgPipeline):
|
||||
(pre_latents[:, :, -2:-1]).clone().repeat_interleave(post_pad_num, 2)], dim=2)
|
||||
control_latents = control_latents + [control_latents[-1]] * post_pad_num
|
||||
|
||||
drive_idx_chunks[-1] = list(range(drive_idx_chunks[-1][0], paded_video_len))
|
||||
|
||||
scheduler = EulerDiscreteScheduler(
|
||||
num_train_timesteps=1000,
|
||||
beta_start=0.00085,
|
||||
beta_end=0.012,
|
||||
beta_schedule="scaled_linear",
|
||||
)
|
||||
|
||||
# 5. set timesteps
|
||||
timesteps, num_inference_steps = retrieve_timesteps(
|
||||
self.scheduler, num_inference_steps, device, None, sigmas
|
||||
scheduler, num_inference_steps, device, None, sigmas
|
||||
)
|
||||
timesteps, num_inference_steps = self.get_timesteps(num_inference_steps, strength, device)
|
||||
latent_timestep = timesteps[:1].repeat(batch_size * num_images_per_prompt)
|
||||
|
||||
# 8. Denoising loop
|
||||
num_warmup_steps = len(timesteps) - num_inference_steps * self.scheduler.order
|
||||
num_warmup_steps = len(timesteps) - num_inference_steps * scheduler.order
|
||||
self._num_timesteps = len(timesteps)
|
||||
|
||||
base_noise = randn_tensor([batch_size, c, paded_video_len, h, w], dtype=prompt_embeds.dtype, generator=generator)
|
||||
latents = self.scheduler.add_noise(pre_latents, base_noise, latent_timestep)
|
||||
|
||||
drive_idx_chunks[-1] = list(range(drive_idx_chunks[-1][0], paded_video_len))
|
||||
latents = scheduler.add_noise(pre_latents, base_noise, latent_timestep)
|
||||
|
||||
with self.progress_bar(total=num_inference_steps) as progress_bar:
|
||||
for i, t in enumerate(timesteps):
|
||||
@@ -322,7 +358,7 @@ class HMVideoPipeline(StableDiffusionImg2ImgPipeline):
|
||||
latent_model_input_all = torch.cat([latents.clone(), latents.clone()], dim=0) if \
|
||||
self.do_classifier_free_guidance else latents.clone()
|
||||
|
||||
latent_model_input_all = self.scheduler.scale_model_input(latent_model_input_all, t)
|
||||
latent_model_input_all = scheduler.scale_model_input(latent_model_input_all, t)
|
||||
for cidx, chunk in enumerate(drive_idx_chunks):
|
||||
if self.interrupt:
|
||||
continue
|
||||
@@ -353,8 +389,8 @@ class HMVideoPipeline(StableDiffusionImg2ImgPipeline):
|
||||
noise_pred = noise_pred_uncond + self.guidance_scale * (noise_pred_text - noise_pred_uncond)
|
||||
|
||||
# compute the previous noisy sample x_t -> x_t-1
|
||||
latents = self.scheduler.step(noise_pred.to(device=device), t, latents.to(device=device),
|
||||
**extra_step_kwargs, return_dict=False)[0].cpu()
|
||||
latents = scheduler.step(noise_pred.cpu(), t, latents,
|
||||
**extra_step_kwargs, return_dict=False)[0]
|
||||
|
||||
if callback_on_step_end is not None:
|
||||
callback_kwargs = {}
|
||||
@@ -367,16 +403,22 @@ class HMVideoPipeline(StableDiffusionImg2ImgPipeline):
|
||||
negative_prompt_embeds = callback_outputs.pop("negative_prompt_embeds", negative_prompt_embeds)
|
||||
|
||||
# call the callback, if provided
|
||||
if i == len(timesteps) - 1 or ((i + 1) > num_warmup_steps and (i + 1) % self.scheduler.order == 0):
|
||||
if i == len(timesteps) - 1 or ((i + 1) > num_warmup_steps and (i + 1) % scheduler.order == 0):
|
||||
progress_bar.set_description(f"GEN stage2")
|
||||
progress_bar.update()
|
||||
if callback is not None and i % callback_steps == 0:
|
||||
step_idx = i // getattr(self.scheduler, "order", 1)
|
||||
step_idx = i // getattr(scheduler, "order", 1)
|
||||
callback(step_idx, t, latents)
|
||||
|
||||
latents = latents / self.vae.config.scaling_factor
|
||||
|
||||
res_frames = [self.vae.decode(latents[:,:,i,:,:].to(device=device), return_dict=False, generator=generator)[0]
|
||||
for i in range(raw_video_len)]
|
||||
res_frames = [self.image_processor.postprocess(frame, output_type=output_type) for frame in res_frames]
|
||||
res_frames = []
|
||||
with self.progress_bar(total=raw_video_len) as progress_bar:
|
||||
for i in range(raw_video_len):
|
||||
ret_tensor = self.vae.decode(latents[:, :, i, :, :].to(device=device),
|
||||
return_dict=False, generator=generator)[0]
|
||||
ret_image = self.image_processor.postprocess(ret_tensor, output_type=output_type)
|
||||
res_frames.append(ret_image)
|
||||
progress_bar.set_description(f"VAE DECODE")
|
||||
progress_bar.update()
|
||||
return res_frames
|
||||
@@ -1,304 +0,0 @@
|
||||
# coding: utf-8
|
||||
|
||||
"""
|
||||
@File : hm_pipline_image.py
|
||||
@Author : Songkey
|
||||
@Email : songkey@pku.edu.cn
|
||||
@Date : 8/29/2024
|
||||
@Desc :
|
||||
adapted from: https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion_img2img.py
|
||||
"""
|
||||
import copy
|
||||
import time
|
||||
from typing import Any, Callable, Dict, List, Optional, Union
|
||||
import torch
|
||||
|
||||
from diffusers.callbacks import MultiPipelineCallbacks, PipelineCallback
|
||||
from diffusers.image_processor import PipelineImageInput
|
||||
from diffusers.utils import deprecate
|
||||
from diffusers.utils.torch_utils import randn_tensor
|
||||
|
||||
from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion_img2img import retrieve_timesteps, retrieve_latents
|
||||
from diffusers import StableDiffusionImg2ImgPipeline, EulerDiscreteScheduler
|
||||
|
||||
from ..models import HMDenoising3D, HMControlNet
|
||||
from ..models import HMReferenceAdapter
|
||||
from ..utils import dicts_to_device, cat_dicts
|
||||
|
||||
class HMVideoSimplePipeline(StableDiffusionImg2ImgPipeline):
|
||||
def caryomitosis(self, **kwargs):
|
||||
if hasattr(self, "unet_ref"):
|
||||
del self.unet_ref
|
||||
self.unet_ref = HMDenoising3D.from_unet2d(self.unet)
|
||||
unet = HMDenoising3D.from_unet2d(self.unet)
|
||||
# todo: 不够优雅
|
||||
del self.unet
|
||||
self.unet = unet
|
||||
|
||||
def insert_hm_modules(self, dtype, device):
|
||||
hm_adapter = HMReferenceAdapter.from_pretrained('songkey/hm_reference')
|
||||
if isinstance(self.unet, HMDenoising3D):
|
||||
self.unet.insert_reference_adapter(hm_adapter)
|
||||
self.unet = self.unet.to(device=device, dtype=dtype).eval()
|
||||
|
||||
if hasattr(self, "unet_ref"):
|
||||
self.unet_ref = self.unet_ref.to(device=device, dtype=dtype).eval()
|
||||
|
||||
if hasattr(self, "mp_control"):
|
||||
del self.mp_control
|
||||
self.mp_control = HMControlNet.from_pretrained('songkey/hm_control')
|
||||
self.mp_control = self.mp_control.to(device=device, dtype=dtype).eval()
|
||||
|
||||
@torch.no_grad()
|
||||
def __call__(
|
||||
self,
|
||||
prompt: Union[str, List[str]] = None,
|
||||
image: PipelineImageInput = None,
|
||||
drive_params: Dict[str, Any] = None,
|
||||
strength: float = 0.8,
|
||||
num_inference_steps: Optional[int] = 50,
|
||||
timesteps: List[int] = None,
|
||||
sigmas: List[float] = None,
|
||||
guidance_scale: Optional[float] = 7.5,
|
||||
negative_prompt: Optional[Union[str, List[str]]] = None,
|
||||
eta: Optional[float] = 0.0,
|
||||
generator: Optional[Union[torch.Generator, List[torch.Generator]]] = None,
|
||||
prompt_embeds: Optional[torch.Tensor] = None,
|
||||
negative_prompt_embeds: Optional[torch.Tensor] = None,
|
||||
ip_adapter_image: Optional[PipelineImageInput] = None,
|
||||
ip_adapter_image_embeds: Optional[List[torch.Tensor]] = None,
|
||||
output_type: Optional[str] = "pil",
|
||||
return_dict: bool = True,
|
||||
cross_attention_kwargs: Optional[Dict[str, Any]] = None,
|
||||
clip_skip: int = None,
|
||||
callback_on_step_end: Optional[
|
||||
Union[Callable[[int, int, Dict], None], PipelineCallback, MultiPipelineCallbacks]
|
||||
] = None,
|
||||
callback_on_step_end_tensor_inputs: List[str] = ["latents"],
|
||||
**kwargs,
|
||||
):
|
||||
callback = kwargs.pop("callback", None)
|
||||
callback_steps = kwargs.pop("callback_steps", None)
|
||||
num_images_per_prompt = 1
|
||||
|
||||
if callback is not None:
|
||||
deprecate(
|
||||
"callback",
|
||||
"1.0.0",
|
||||
"Passing `callback` as an input argument to `__call__` is deprecated, consider use `callback_on_step_end`",
|
||||
)
|
||||
if callback_steps is not None:
|
||||
deprecate(
|
||||
"callback_steps",
|
||||
"1.0.0",
|
||||
"Passing `callback_steps` as an input argument to `__call__` is deprecated, consider use `callback_on_step_end`",
|
||||
)
|
||||
|
||||
if isinstance(callback_on_step_end, (PipelineCallback, MultiPipelineCallbacks)):
|
||||
callback_on_step_end_tensor_inputs = callback_on_step_end.tensor_inputs
|
||||
|
||||
# 1. Check inputs. Raise error if not correct
|
||||
self.check_inputs(
|
||||
prompt,
|
||||
strength,
|
||||
callback_steps,
|
||||
negative_prompt,
|
||||
prompt_embeds,
|
||||
negative_prompt_embeds,
|
||||
ip_adapter_image,
|
||||
ip_adapter_image_embeds,
|
||||
callback_on_step_end_tensor_inputs,
|
||||
)
|
||||
|
||||
self._guidance_scale = guidance_scale
|
||||
self._clip_skip = clip_skip
|
||||
self._cross_attention_kwargs = cross_attention_kwargs
|
||||
self._interrupt = False
|
||||
|
||||
# 2. Define call parameters
|
||||
if prompt is not None and isinstance(prompt, str):
|
||||
batch_size = 1
|
||||
elif prompt is not None and isinstance(prompt, list):
|
||||
batch_size = len(prompt)
|
||||
else:
|
||||
batch_size = prompt_embeds.shape[0]
|
||||
|
||||
device = self._execution_device
|
||||
|
||||
# 3. Encode input prompt
|
||||
text_encoder_lora_scale = (
|
||||
self.cross_attention_kwargs.get("scale", None) if self.cross_attention_kwargs is not None else None
|
||||
)
|
||||
prompt_embeds, negative_prompt_embeds = self.encode_prompt(
|
||||
prompt,
|
||||
device,
|
||||
num_images_per_prompt,
|
||||
self.do_classifier_free_guidance,
|
||||
negative_prompt,
|
||||
prompt_embeds=prompt_embeds,
|
||||
negative_prompt_embeds=negative_prompt_embeds,
|
||||
lora_scale=text_encoder_lora_scale,
|
||||
clip_skip=self.clip_skip,
|
||||
)
|
||||
# For classifier free guidance, we need to do two forward passes.
|
||||
# Here we concatenate the unconditional and text embeddings into a single batch
|
||||
# to avoid doing two forward passes
|
||||
if self.do_classifier_free_guidance:
|
||||
prompt_embeds = torch.cat([negative_prompt_embeds, prompt_embeds])
|
||||
|
||||
if ip_adapter_image is not None or ip_adapter_image_embeds is not None:
|
||||
image_embeds = self.prepare_ip_adapter_image_embeds(
|
||||
ip_adapter_image,
|
||||
ip_adapter_image_embeds,
|
||||
device,
|
||||
batch_size * num_images_per_prompt,
|
||||
self.do_classifier_free_guidance,
|
||||
)
|
||||
|
||||
# 4. Preprocess image
|
||||
image = self.image_processor.preprocess(image).to(device=device, dtype=prompt_embeds.dtype)
|
||||
|
||||
# 6. Prepare latent variables
|
||||
ref_latents = [
|
||||
retrieve_latents(self.vae.encode(image[i: i + 1].to(device=device)), generator=generator)
|
||||
for i in range(batch_size)
|
||||
]
|
||||
ref_latents = torch.cat(ref_latents, dim=0)
|
||||
ref_latents = self.vae.config.scaling_factor * ref_latents
|
||||
c, h, w = ref_latents.shape[1:]
|
||||
|
||||
# 7. Prepare extra step kwargs. TODO: Logic should ideally just be moved out of the pipeline
|
||||
extra_step_kwargs = self.prepare_extra_step_kwargs(generator, eta)
|
||||
|
||||
# 7.1 Add image embeds for IP-Adapter
|
||||
added_cond_kwargs = (
|
||||
{"image_embeds": image_embeds}
|
||||
if ip_adapter_image is not None or ip_adapter_image_embeds is not None
|
||||
else None
|
||||
)
|
||||
|
||||
ref_latents = ref_latents.unsqueeze(2)
|
||||
cached_res = self.unet_ref(
|
||||
torch.cat([torch.zeros_like(ref_latents), ref_latents], dim=0) if
|
||||
self.do_classifier_free_guidance else ref_latents,
|
||||
0,
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
return_dict=False,
|
||||
)[1]
|
||||
|
||||
# 7.2 Optionally get Guidance Scale Embedding
|
||||
timestep_cond = None
|
||||
if self.unet.config.time_cond_proj_dim is not None:
|
||||
guidance_scale_tensor = torch.tensor(self.guidance_scale - 1).repeat(batch_size * num_images_per_prompt)
|
||||
timestep_cond = self.get_guidance_scale_embedding(
|
||||
guidance_scale_tensor, embedding_dim=self.unet.config.time_cond_proj_dim
|
||||
).to(device=device, dtype=prompt_embeds.dtype)
|
||||
|
||||
raw_video_len = drive_params['condition'].size(2)
|
||||
|
||||
pre_latents = []
|
||||
control_latents = []
|
||||
control_latent_neg = None
|
||||
base_noise = randn_tensor([batch_size, c, 1, h, w], dtype=prompt_embeds.dtype, generator=generator).to(device=device)
|
||||
with self.progress_bar(total=raw_video_len) as progress_bar:
|
||||
for idx in range(raw_video_len):
|
||||
condition = drive_params['condition'][:, :, idx:idx+1].clone().to(device=device)
|
||||
drive_coeff = drive_params['drive_coeff'][:, idx:idx+1].clone().to(device=device)
|
||||
face_parts = drive_params['face_parts'][:, idx:idx+1].clone().to(device=device)
|
||||
|
||||
if control_latent_neg is None and self.do_classifier_free_guidance:
|
||||
control_latent_neg = self.mp_control(condition=torch.ones_like(condition)*-1,
|
||||
drive_coeff=torch.zeros_like(drive_coeff),
|
||||
face_parts=torch.zeros_like(face_parts))
|
||||
|
||||
control_latent = self.mp_control(condition=condition,
|
||||
drive_coeff=drive_coeff,
|
||||
face_parts=face_parts)
|
||||
if self.do_classifier_free_guidance:
|
||||
control_latent = cat_dicts([control_latent_neg, control_latent], dim=0)
|
||||
|
||||
scheduler = EulerDiscreteScheduler(
|
||||
num_train_timesteps=1000,
|
||||
beta_start=0.00085,
|
||||
beta_end=0.012,
|
||||
beta_schedule="scaled_linear",
|
||||
)
|
||||
|
||||
tmp_timesteps, _ = retrieve_timesteps(scheduler, 8, device, None, sigmas)
|
||||
# pred_latent = scheduler.add_noise(ref_latents, base_noise, tmp_timesteps[:1])
|
||||
if idx == 0:
|
||||
pred_latent = scheduler.add_noise(ref_latents, base_noise, tmp_timesteps[:1])
|
||||
else:
|
||||
pred_latent = scheduler.add_noise(pred_latent, base_noise, tmp_timesteps[:1])
|
||||
|
||||
for i, t in enumerate(tmp_timesteps):
|
||||
latent_model_input = torch.cat([pred_latent, pred_latent], dim=0) if \
|
||||
self.do_classifier_free_guidance else pred_latent
|
||||
latent_model_input = scheduler.scale_model_input(latent_model_input, t)
|
||||
noise_pred_chunk = self.unet(
|
||||
latent_model_input,
|
||||
t,
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
reference_hidden_states=cached_res,
|
||||
control_hidden_states=control_latent,
|
||||
timestep_cond=timestep_cond,
|
||||
cross_attention_kwargs=self.cross_attention_kwargs,
|
||||
added_cond_kwargs=added_cond_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
if self.do_classifier_free_guidance:
|
||||
noise_pred_uncond, noise_pred_text = noise_pred_chunk.chunk(2)
|
||||
noise_pred_chunk = noise_pred_uncond + self.guidance_scale * (noise_pred_text - noise_pred_uncond)
|
||||
pred_latent = scheduler.step(noise_pred_chunk, t, pred_latent,
|
||||
**extra_step_kwargs, return_dict=False)[0]
|
||||
pre_latents.append(pred_latent.cpu())
|
||||
control_latents.append(dicts_to_device([control_latent], device='cpu')[0])
|
||||
|
||||
progress_bar.set_description(f"GEN stage1")
|
||||
progress_bar.update()
|
||||
|
||||
res_frames = []
|
||||
with self.progress_bar(total=raw_video_len) as progress_bar:
|
||||
for idx in range(raw_video_len):
|
||||
|
||||
scheduler = EulerDiscreteScheduler(
|
||||
num_train_timesteps=1000,
|
||||
beta_start=0.00085,
|
||||
beta_end=0.012,
|
||||
beta_schedule="scaled_linear",
|
||||
)
|
||||
tmp_timesteps, _ = retrieve_timesteps(scheduler, num_inference_steps, device, None, sigmas)
|
||||
|
||||
res_latent = scheduler.add_noise(pre_latents[idx].to(device=device), base_noise, tmp_timesteps[:1])
|
||||
|
||||
for i, t in enumerate(tmp_timesteps):
|
||||
latent_model_input = torch.cat([res_latent, res_latent], dim=0) if \
|
||||
self.do_classifier_free_guidance else res_latent
|
||||
latent_model_input = scheduler.scale_model_input(latent_model_input, t)
|
||||
noise_pred = self.unet(
|
||||
latent_model_input,
|
||||
t,
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
reference_hidden_states=cached_res,
|
||||
control_hidden_states=dicts_to_device([control_latents[idx]], device=device)[0],
|
||||
timestep_cond=timestep_cond,
|
||||
cross_attention_kwargs=self.cross_attention_kwargs,
|
||||
added_cond_kwargs=added_cond_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
if self.do_classifier_free_guidance:
|
||||
noise_pred_uncond, noise_pred_text = noise_pred.chunk(2)
|
||||
noise_pred = noise_pred_uncond + self.guidance_scale * (
|
||||
noise_pred_text - noise_pred_uncond)
|
||||
res_latent = scheduler.step(noise_pred, t, res_latent,
|
||||
**extra_step_kwargs, return_dict=False)[0]
|
||||
|
||||
res_frame_tensor = self.vae.decode(res_latent[:,:,0,:,:].to(device=device) / self.vae.config.scaling_factor,
|
||||
return_dict=False, generator=generator)[0]
|
||||
res_frame = self.image_processor.postprocess(res_frame_tensor, output_type=output_type)
|
||||
|
||||
res_frames.append(res_frame)
|
||||
|
||||
progress_bar.set_description(f"GEN stage2")
|
||||
progress_bar.update()
|
||||
return res_frames
|
||||
@@ -11,3 +11,4 @@ from .hello_face_det import HelloFaceDet
|
||||
from .hello_camera_demo import HelloCameraDemo
|
||||
from .hello_3dmm import Hello3DMMPred
|
||||
from .hello_face_alignment import HelloFaceAlignment
|
||||
from .pdf import FanEncoder
|
||||
|
||||
@@ -0,0 +1,208 @@
|
||||
# coding: utf-8
|
||||
|
||||
"""
|
||||
@File : pdf.py
|
||||
@Author : Songkey
|
||||
@Email : songkey@pku.edu.cn
|
||||
@Date : 11/7/2024
|
||||
@Desc : Adapted from: https://github.com/Dorniwang/PD-FGC-inference/blob/main/lib/models/networks/encoder.py
|
||||
"""
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
|
||||
from diffusers.models.modeling_utils import ModelMixin
|
||||
from diffusers.configuration_utils import ConfigMixin, register_to_config
|
||||
|
||||
def conv3x3(in_planes, out_planes, strd=1, padding=1, bias=False):
|
||||
"3x3 convolution with padding"
|
||||
return nn.Conv2d(in_planes, out_planes, kernel_size=3,
|
||||
stride=strd, padding=padding, bias=bias)
|
||||
|
||||
class ConvBlock(nn.Module):
|
||||
def __init__(self, in_planes, out_planes):
|
||||
super(ConvBlock, self).__init__()
|
||||
self.bn1 = nn.BatchNorm2d(in_planes)
|
||||
self.conv1 = conv3x3(in_planes, int(out_planes / 2))
|
||||
self.bn2 = nn.BatchNorm2d(int(out_planes / 2))
|
||||
self.conv2 = conv3x3(int(out_planes / 2), int(out_planes / 4))
|
||||
self.bn3 = nn.BatchNorm2d(int(out_planes / 4))
|
||||
self.conv3 = conv3x3(int(out_planes / 4), int(out_planes / 4))
|
||||
|
||||
if in_planes != out_planes:
|
||||
self.downsample = nn.Sequential(
|
||||
nn.BatchNorm2d(in_planes),
|
||||
nn.ReLU(True),
|
||||
nn.Conv2d(in_planes, out_planes,
|
||||
kernel_size=1, stride=1, bias=False),
|
||||
)
|
||||
else:
|
||||
self.downsample = None
|
||||
|
||||
def forward(self, x):
|
||||
residual = x
|
||||
|
||||
out1 = self.bn1(x)
|
||||
out1 = F.relu(out1, True)
|
||||
out1 = self.conv1(out1)
|
||||
|
||||
out2 = self.bn2(out1)
|
||||
out2 = F.relu(out2, True)
|
||||
out2 = self.conv2(out2)
|
||||
|
||||
out3 = self.bn3(out2)
|
||||
out3 = F.relu(out3, True)
|
||||
out3 = self.conv3(out3)
|
||||
|
||||
out3 = torch.cat((out1, out2, out3), 1)
|
||||
|
||||
if self.downsample is not None:
|
||||
residual = self.downsample(residual)
|
||||
|
||||
out3 += residual
|
||||
|
||||
return out3
|
||||
|
||||
|
||||
class HourGlass(nn.Module):
|
||||
def __init__(self, num_modules, depth, num_features):
|
||||
super(HourGlass, self).__init__()
|
||||
self.num_modules = num_modules
|
||||
self.depth = depth
|
||||
self.features = num_features
|
||||
self.dropout = nn.Dropout(0.5)
|
||||
|
||||
self._generate_network(self.depth)
|
||||
|
||||
def _generate_network(self, level):
|
||||
self.add_module('b1_' + str(level), ConvBlock(256, 256))
|
||||
|
||||
self.add_module('b2_' + str(level), ConvBlock(256, 256))
|
||||
|
||||
if level > 1:
|
||||
self._generate_network(level - 1)
|
||||
else:
|
||||
self.add_module('b2_plus_' + str(level), ConvBlock(256, 256))
|
||||
|
||||
self.add_module('b3_' + str(level), ConvBlock(256, 256))
|
||||
|
||||
def _forward(self, level, inp):
|
||||
# Upper branch
|
||||
up1 = inp
|
||||
up1 = self._modules['b1_' + str(level)](up1)
|
||||
up1 = self.dropout(up1)
|
||||
# Lower branch
|
||||
low1 = F.max_pool2d(inp, 2, stride=2)
|
||||
low1 = self._modules['b2_' + str(level)](low1)
|
||||
|
||||
if level > 1:
|
||||
low2 = self._forward(level - 1, low1)
|
||||
else:
|
||||
low2 = low1
|
||||
low2 = self._modules['b2_plus_' + str(level)](low2)
|
||||
|
||||
low3 = low2
|
||||
low3 = self._modules['b3_' + str(level)](low3)
|
||||
up1size = up1.size()
|
||||
rescale_size = (up1size[2], up1size[3])
|
||||
up2 = F.upsample(low3, size=rescale_size, mode='bilinear')
|
||||
|
||||
return up1 + up2
|
||||
|
||||
def forward(self, x):
|
||||
return self._forward(self.depth, x)
|
||||
|
||||
class FAN_use(nn.Module):
|
||||
def __init__(self):
|
||||
super(FAN_use, self).__init__()
|
||||
self.num_modules = 1
|
||||
|
||||
# Base part
|
||||
self.conv1 = nn.Conv2d(3, 64, kernel_size=7, stride=2, padding=3)
|
||||
self.bn1 = nn.BatchNorm2d(64)
|
||||
self.conv2 = ConvBlock(64, 128)
|
||||
self.conv3 = ConvBlock(128, 128)
|
||||
self.conv4 = ConvBlock(128, 256)
|
||||
|
||||
# Stacking part
|
||||
hg_module = 0
|
||||
self.add_module('m' + str(hg_module), HourGlass(1, 4, 256))
|
||||
self.add_module('top_m_' + str(hg_module), ConvBlock(256, 256))
|
||||
self.add_module('conv_last' + str(hg_module),
|
||||
nn.Conv2d(256, 256, kernel_size=1, stride=1, padding=0))
|
||||
self.add_module('l' + str(hg_module), nn.Conv2d(256,
|
||||
68, kernel_size=1, stride=1, padding=0))
|
||||
self.add_module('bn_end' + str(hg_module), nn.BatchNorm2d(256))
|
||||
|
||||
if hg_module < self.num_modules - 1:
|
||||
self.add_module(
|
||||
'bl' + str(hg_module), nn.Conv2d(256, 256, kernel_size=1, stride=1, padding=0))
|
||||
self.add_module('al' + str(hg_module), nn.Conv2d(68,
|
||||
256, kernel_size=1, stride=1, padding=0))
|
||||
|
||||
self.avgpool = nn.MaxPool2d((2, 2), 2)
|
||||
self.conv6 = nn.Conv2d(68, 1, 3, 2, 1)
|
||||
self.fc = nn.Linear(28 * 28, 512)
|
||||
self.bn5 = nn.BatchNorm2d(68)
|
||||
self.relu = nn.ReLU(True)
|
||||
|
||||
def forward(self, x):
|
||||
x = F.relu(self.bn1(self.conv1(x)), True)
|
||||
x = F.max_pool2d(self.conv2(x), 2)
|
||||
x = self.conv3(x)
|
||||
x = self.conv4(x)
|
||||
|
||||
previous = x
|
||||
|
||||
i = 0
|
||||
hg = self._modules['m' + str(i)](previous)
|
||||
|
||||
ll = hg
|
||||
ll = self._modules['top_m_' + str(i)](ll)
|
||||
|
||||
ll = self._modules['bn_end' + str(i)](self._modules['conv_last' + str(i)](ll))
|
||||
tmp_out = self._modules['l' + str(i)](F.relu(ll))
|
||||
|
||||
net = self.relu(self.bn5(tmp_out))
|
||||
net = self.conv6(net)
|
||||
net = net.view(-1, net.shape[-2] * net.shape[-1])
|
||||
net = self.relu(net)
|
||||
net = self.fc(net)
|
||||
return net
|
||||
|
||||
class FanEncoder(ModelMixin, ConfigMixin):
|
||||
@register_to_config
|
||||
def __init__(self,pose_dim=6, eye_dim=6):
|
||||
super().__init__()
|
||||
|
||||
self.model = FAN_use()
|
||||
|
||||
self.to_mouth = nn.Sequential(nn.Linear(512, 512), nn.ReLU(), nn.BatchNorm1d(512), nn.Linear(512, 512))
|
||||
self.mouth_embed = nn.Sequential(nn.ReLU(), nn.Linear(512, 512 - pose_dim - eye_dim))
|
||||
|
||||
# self.to_headpose = nn.Sequential(nn.Linear(512, 512), nn.ReLU(), nn.BatchNorm1d(512), nn.Linear(512, 512))
|
||||
# self.headpose_embed = nn.Sequential(nn.ReLU(), nn.Linear(512, pose_dim))
|
||||
|
||||
self.to_eye = nn.Sequential(nn.Linear(512, 512), nn.ReLU(), nn.BatchNorm1d(512), nn.Linear(512, 512))
|
||||
self.eye_embed = nn.Sequential(nn.ReLU(), nn.Linear(512, eye_dim))
|
||||
|
||||
self.to_emo = nn.Sequential(nn.Linear(512, 512), nn.ReLU(), nn.BatchNorm1d(512), nn.Linear(512, 512))
|
||||
self.emo_embed = nn.Sequential(nn.ReLU(), nn.Linear(512, 30))
|
||||
|
||||
def forward_feature(self, x):
|
||||
net = self.model(x)
|
||||
return net
|
||||
|
||||
def forward(self, x):
|
||||
x = self.model(x)
|
||||
mouth_feat = self.to_mouth(x)
|
||||
# headpose_feat = self.to_headpose(x)
|
||||
# headpose_emb = self.headpose_embed(headpose_feat)
|
||||
eye_feat = self.to_eye(x)
|
||||
eye_embed = self.eye_embed(eye_feat)
|
||||
emo_feat = self.to_emo(x)
|
||||
emo_embed = self.emo_embed(emo_feat)
|
||||
|
||||
return torch.cat([eye_embed, emo_embed, mouth_feat], dim=1)
|
||||
# return headpose_emb, eye_embed, emo_embed, mouth_feat
|
||||
+157
-124
@@ -22,18 +22,21 @@ from diffusers.pipelines.stable_diffusion.convert_from_ckpt import convert_ldm_u
|
||||
|
||||
from safetensors import safe_open
|
||||
|
||||
|
||||
def merge_dicts(dictl, dictr, wl=0.5):
|
||||
res = {}
|
||||
for k in dictl.keys():
|
||||
res[k] = dictl[k] * wl + dictr[k] * (1-wl)
|
||||
return res
|
||||
|
||||
|
||||
def cat_dicts(dicts, dim=0):
|
||||
res = {}
|
||||
for k in dicts[0].keys():
|
||||
res[k] = torch.cat([d[k].clone() for d in dicts], dim=dim)
|
||||
return res
|
||||
|
||||
|
||||
def dicts_to_device(dicts, device):
|
||||
ret = []
|
||||
for d in dicts:
|
||||
@@ -43,6 +46,7 @@ def dicts_to_device(dicts, device):
|
||||
ret.append(tmpd)
|
||||
return ret
|
||||
|
||||
|
||||
def load_safetensors(model_path):
|
||||
tensors = {}
|
||||
with safe_open(model_path, framework="pt", device=0) as f:
|
||||
@@ -50,22 +54,27 @@ def load_safetensors(model_path):
|
||||
tensors[k] = f.get_tensor(k) # loads the full tensor given a key
|
||||
return tensors
|
||||
|
||||
|
||||
def load_unet_from_safetensors(safetensors_path, unet_config):
|
||||
original_stats = load_safetensors(safetensors_path)
|
||||
return convert_ldm_unet_checkpoint(original_stats, unet_config)
|
||||
|
||||
|
||||
def image_preprocess(np_bgr, size, dtype=torch.float32):
|
||||
img_np = cv2.resize(np_bgr, size)
|
||||
return np_bgr_to_tensor(img_np, dtype)
|
||||
|
||||
|
||||
def np_bgr_to_tensor(img_np, dtype):
|
||||
img_rgb = cv2.cvtColor(img_np, cv2.COLOR_BGR2RGB) / 255. * 2 - 1
|
||||
return torch.tensor(img_rgb).permute(2, 0, 1).to(dtype=dtype)
|
||||
|
||||
|
||||
def tensor_to_np_rgb(img_np):
|
||||
img_rgb = np.clip((img_np.permute(1, 2, 0).detach().cpu().numpy() + 1) / 2 * 255, 0, 255)
|
||||
return img_rgb.astype(np.uint8)
|
||||
|
||||
|
||||
def clip_preprocess_from_bgr(image_bgr, dtype=torch.float32):
|
||||
temp_image = cv2.resize(image_bgr, (224, 224), interpolation=cv2.INTER_CUBIC)
|
||||
temp_image = cv2.cvtColor(temp_image, cv2.COLOR_BGR2RGB)
|
||||
@@ -74,6 +83,7 @@ def clip_preprocess_from_bgr(image_bgr, dtype=torch.float32):
|
||||
temp_image_np = np.transpose(temp_image_np, (2, 0, 1))
|
||||
return torch.tensor(temp_image_np, dtype=dtype)
|
||||
|
||||
|
||||
def clip_preprocess_to_bgr(image_tensor):
|
||||
image_tensor_np = image_tensor.detach().cpu().numpy().astype(float)
|
||||
image_tensor_np = np.transpose(image_tensor_np, (1, 2, 0))
|
||||
@@ -81,6 +91,7 @@ def clip_preprocess_to_bgr(image_tensor):
|
||||
image_tensor_np = np.clip(image_tensor_np / 0.00392156862745098, 0, 255).astype(np.uint8)
|
||||
return cv2.cvtColor(image_tensor_np, cv2.COLOR_BGR2RGB)
|
||||
|
||||
|
||||
def clip_preprocess_from_pil(image_pil, dtype):
|
||||
temp_image = image_pil.resize((224, 224), resample=Image.BICUBIC)
|
||||
temp_image_np = np.asarray(temp_image) * 0.00392156862745098
|
||||
@@ -88,6 +99,7 @@ def clip_preprocess_from_pil(image_pil, dtype):
|
||||
temp_image_np = np.transpose(temp_image_np, (2, 0, 1))
|
||||
return torch.tensor(temp_image_np, dtype=dtype)
|
||||
|
||||
|
||||
def draw_skl_by_rect(save_size, rect):
|
||||
rect = rect.astype(np.int32)
|
||||
ret_img = np.zeros((save_size, save_size, 3), dtype=np.uint8)
|
||||
@@ -98,21 +110,6 @@ def draw_skl_by_rect(save_size, rect):
|
||||
cv2.line(ret_img, rect[3], rect[0], (255, 0, 255), 15)
|
||||
return ret_img
|
||||
|
||||
def get_face_part_1frame(image, parts, save_size=256):
|
||||
ret_list = []
|
||||
for part_landmarks in parts:
|
||||
part_tls, part_brs = np.min(part_landmarks, axis=0), np.max(part_landmarks, axis=0)
|
||||
center = (part_tls + part_brs) * 0.5
|
||||
wh = max(part_brs - part_tls) * 1.2
|
||||
|
||||
scale = save_size / wh
|
||||
|
||||
M = cv2.getRotationMatrix2D(center, 0, scale)
|
||||
M[:, 2] += save_size * 0.5 - center
|
||||
|
||||
part = cv2.warpAffine(image, M, (save_size, save_size))
|
||||
ret_list.append(part)
|
||||
return np.stack(ret_list, axis=0)
|
||||
|
||||
face_parts_regions = [
|
||||
[48, 49, 50, 51, 52, 53, 54, 55, 56, 57, 58, 59, 74, 75, 76, 77, 78, 79, 80, 81, 82, 83, 84, 85, 86, 87, 88, 89, 90, 91, 92, 93, 94],
|
||||
@@ -122,7 +119,112 @@ face_parts_regions = [
|
||||
face_region = [33, 74, 96, 133, 149]
|
||||
face_temp = np.array([[0.50951539, 0.40128625], [0.29259476, 0.40203411], [0.72196212, 0.40857479], [0.63420714, 0.71678643], [0.38437035, 0.71723224]])
|
||||
|
||||
def get_face_parts(images, landmarks, save_size=256):
|
||||
|
||||
def get_drive_pose(toolkits, frames, landmarks, save_size=512, align=True):
|
||||
if align:
|
||||
new_frames, new_landmarks = crop_and_resize(np.stack(frames, axis=0), np.stack(landmarks, axis=0),
|
||||
save_size=save_size, crop=False)
|
||||
else:
|
||||
new_frames, new_landmarks = frames, landmarks
|
||||
|
||||
rot_list = []
|
||||
trans_list = []
|
||||
with tqdm(total=len(new_landmarks)) as pbar:
|
||||
for landmark, frame in zip(new_landmarks, new_frames):
|
||||
drive_rot, drive_trans = toolkits['h3dmm'].forward_params(frame, landmark)
|
||||
rot_list.append(drive_rot)
|
||||
trans_list.append(drive_trans)
|
||||
|
||||
pbar.set_description('HEAD POSE')
|
||||
pbar.update()
|
||||
return rot_list, trans_list
|
||||
|
||||
|
||||
def get_drive_expression(toolkits, images, landmarks):
|
||||
face_parts_embedding = get_face_parts(toolkits, images, landmarks, save_size=256)
|
||||
drive_coeff = get_arkit_bs(toolkits, images, landmarks)
|
||||
|
||||
return dict(
|
||||
face_parts=face_parts_embedding.unsqueeze(0),
|
||||
drive_coeff=drive_coeff.unsqueeze(0)
|
||||
)
|
||||
|
||||
|
||||
def get_drive_expression_pd_fgc(toolkits, images, landmarks):
|
||||
dtype = toolkits['dtype']
|
||||
device = toolkits['device']
|
||||
emo_list = []
|
||||
|
||||
motion_model = toolkits['pd_fpg_motion'].to(device=device)
|
||||
with tqdm(total=len(images)) as pbar:
|
||||
for frame, landmark in zip(images, landmarks):
|
||||
emo_image = warp_face_pd_fgc(frame, landmark, save_size=224)
|
||||
input_tensor = image_preprocess(emo_image, (224, 224), dtype).to(device=device).unsqueeze(0)
|
||||
emo_tensor = motion_model(input_tensor)
|
||||
emo_list.append(emo_tensor.cpu())
|
||||
pbar.set_description('PD_FPG_MOTION')
|
||||
pbar.update()
|
||||
|
||||
neg_tensor = motion_model(torch.ones_like(input_tensor)*-1).cpu()
|
||||
|
||||
ret_tensor = torch.cat(emo_list, dim=0)
|
||||
toolkits['pd_fpg_motion'].to(device='cpu')
|
||||
return dict(pd_fpg=ret_tensor.unsqueeze(0), neg_pd_fpg=neg_tensor.unsqueeze(0))
|
||||
|
||||
|
||||
def gen_control_heatmaps(drive_rot, drive_trans, ref_trans, save_size=512, trans_ratio=0.0):
|
||||
control_list = []
|
||||
for rot, trans in zip(drive_rot, drive_trans):
|
||||
rect = get_project_points_rect(rot, ref_trans + (trans - drive_trans[0]) * trans_ratio, save_size, save_size)
|
||||
control_heatmap = draw_skl_by_rect(save_size, rect)
|
||||
|
||||
control_heatmap = image_preprocess(control_heatmap, (save_size, save_size))
|
||||
control_list.append(control_heatmap)
|
||||
return torch.stack(control_list, dim=1)
|
||||
|
||||
|
||||
def det_landmarks(face_aligner, frame_list):
|
||||
rect_list = []
|
||||
new_frame_list = []
|
||||
|
||||
assert len(frame_list) > 0
|
||||
face_aligner.reset_track()
|
||||
with tqdm(total=len(frame_list)) as pbar:
|
||||
for frame in frame_list:
|
||||
faces = face_aligner.forward(frame)
|
||||
if len(faces) > 0:
|
||||
face = sorted(faces, key=lambda x: (x['face_rect'][2] - x['face_rect'][0]) * (
|
||||
x['face_rect'][3] - x['face_rect'][1]))[-1]
|
||||
rect_list.append(face['face_rect'])
|
||||
new_frame_list.append(frame)
|
||||
pbar.set_description('DET stage1')
|
||||
pbar.update()
|
||||
|
||||
assert len(new_frame_list) > 0
|
||||
face_aligner.reset_track()
|
||||
save_frame_list = []
|
||||
save_landmark_list = []
|
||||
with tqdm(total=len(new_frame_list)) as pbar:
|
||||
for frame, rect in zip(new_frame_list, rect_list):
|
||||
faces = face_aligner.forward(frame, pre_rect=rect)
|
||||
if len(faces) > 0:
|
||||
face = sorted(faces, key=lambda x: (x['face_rect'][2] - x['face_rect'][0]) * (
|
||||
x['face_rect'][3] - x['face_rect'][1]))[-1]
|
||||
landmarks = face['pre_kpt_222']
|
||||
save_frame_list.append(frame)
|
||||
save_landmark_list.append(landmarks)
|
||||
pbar.set_description('DET stage2')
|
||||
pbar.update()
|
||||
|
||||
assert len(save_frame_list) > 0
|
||||
save_landmark_list = np.stack(save_landmark_list, axis=0).astype(np.float16)
|
||||
face_aligner.reset_track()
|
||||
return save_frame_list, save_landmark_list
|
||||
|
||||
|
||||
def get_face_parts(toolkits, images, landmarks, save_size=256):
|
||||
dtype = toolkits['dtype']
|
||||
device = toolkits['device']
|
||||
H, W = images[0].shape[:2]
|
||||
warped_imgs = []
|
||||
warped_landmarks = []
|
||||
@@ -136,138 +238,65 @@ def get_face_parts(images, landmarks, save_size=256):
|
||||
|
||||
warped_landmark = transform_points(landmark.astype(np.float32), M)[:,:2]
|
||||
|
||||
# for x, y in warped_landmark:
|
||||
# warped_img = cv2.circle(warped_img, (int(x), int(y)), 1, (255, 255, 0), -1)
|
||||
# for x, y in dst_landmarks:
|
||||
# warped_img = cv2.circle(warped_img, (int(x), int(y)), 1, (0, 255, 0), -1)
|
||||
# cv2.imshow('warped_img', warped_img)
|
||||
# cv2.waitKey()
|
||||
|
||||
warped_imgs.append(warped_img)
|
||||
warped_landmarks.append(warped_landmark)
|
||||
warped_imgs = np.stack(warped_imgs, axis=0)
|
||||
warped_landmarks = np.stack(warped_landmarks, axis=0)
|
||||
|
||||
ret_list = []
|
||||
for region in face_parts_regions:
|
||||
clip_encoder = toolkits['image_encoder'].to(device=device)
|
||||
|
||||
face_parts_embedding = []
|
||||
|
||||
for rdx, region in enumerate(face_parts_regions):
|
||||
part_landmarks = warped_landmarks[:, region, :]
|
||||
part_tls, part_brs = np.min(np.min(part_landmarks, axis=1), axis=0), np.max(np.max(part_landmarks, axis=1), axis=0)
|
||||
center = (part_tls + part_brs) * 0.5
|
||||
wh = max(part_brs - part_tls) * 1.2
|
||||
|
||||
scale = save_size / wh
|
||||
|
||||
M = cv2.getRotationMatrix2D(center, 0, scale)
|
||||
M[:, 2] += save_size * 0.5 - center
|
||||
tmp_part_list = []
|
||||
for warped_img in warped_imgs:
|
||||
part = cv2.warpAffine(warped_img, M, (save_size, save_size))
|
||||
# cv2.imshow('warped_img', warped_img)
|
||||
# cv2.imshow('part', part)
|
||||
# cv2.waitKey()
|
||||
tmp_part_list.append(part)
|
||||
ret_list.append(np.stack(tmp_part_list, axis=0))
|
||||
return np.stack(ret_list, axis=0).transpose(1, 0, 2, 3, 4)
|
||||
|
||||
def get_face_params(h3dmm, harkit_bs, frames, landmarks, save_size=(512, 512), align=True):
|
||||
face_parts = []
|
||||
for tmp_face_parts_list in get_face_parts(frames, landmarks, save_size=256):
|
||||
tmp_face_parts_list = [cv2.GaussianBlur(x, (9, 9), 0) for x in tmp_face_parts_list]
|
||||
face_parts.append(tmp_face_parts_list)
|
||||
tmp_parts_embeddings = []
|
||||
with tqdm(total=len(warped_imgs)) as pbar:
|
||||
for warped_img in warped_imgs:
|
||||
part = cv2.warpAffine(warped_img, M, (save_size, save_size))
|
||||
part = cv2.GaussianBlur(part, (5, 5), 0)
|
||||
part_input = clip_preprocess_from_bgr(part).unsqueeze(0)
|
||||
part_embedding = clip_encoder(part_input.to(device=device, dtype=dtype)).image_embeds
|
||||
tmp_parts_embeddings.append(part_embedding[0].cpu())
|
||||
|
||||
if align:
|
||||
new_frames, new_landmarks = crop_and_resize(np.stack(frames, axis=0), np.stack(landmarks, axis=0),
|
||||
save_size=save_size, crop=False)
|
||||
else:
|
||||
new_frames, new_landmarks = frames, landmarks
|
||||
pbar.set_description(f'FACE part{rdx}')
|
||||
pbar.update()
|
||||
face_parts_embedding.append(torch.stack(tmp_parts_embeddings, dim=0))
|
||||
|
||||
rot_list = []
|
||||
trans_list = []
|
||||
ret_embedding = torch.stack(face_parts_embedding, dim=0)
|
||||
ret_embedding = rearrange(ret_embedding, "p f d -> f p d")
|
||||
toolkits['image_encoder'].to(device='cpu')
|
||||
return ret_embedding
|
||||
|
||||
|
||||
def get_arkit_bs(toolkits, frames, landmarks):
|
||||
harkit_bs = toolkits['harkit_bs']
|
||||
arkit_bs_list = []
|
||||
|
||||
with tqdm(total=len(new_landmarks)) as pbar:
|
||||
for landmark, frame in zip(new_landmarks, new_frames):
|
||||
drive_rot, drive_trans = h3dmm.forward_params(frame, landmark)
|
||||
rot_list.append(drive_rot)
|
||||
trans_list.append(drive_trans)
|
||||
with tqdm(total=len(landmarks)) as pbar:
|
||||
for landmark, frame in zip(landmarks, frames):
|
||||
arkit_bs_list.append(harkit_bs.forward(frame, landmark))
|
||||
|
||||
pbar.set_description('RT & ARKIT')
|
||||
pbar.set_description('ARKIT BS')
|
||||
pbar.update()
|
||||
drive_coeff = torch.from_numpy(np.stack(arkit_bs_list, axis=0))
|
||||
return face_parts, drive_coeff, rot_list, trans_list
|
||||
return torch.from_numpy(np.stack(arkit_bs_list, axis=0))
|
||||
|
||||
def face_params_to_tensor(clip_encoder, face_parts):
|
||||
face_parts_list = []
|
||||
for tmp_face_parts_list in face_parts:
|
||||
tmp_face_parts_list = [clip_preprocess_from_bgr(x).unsqueeze(1) for x in tmp_face_parts_list]
|
||||
face_parts_list.append(torch.cat(tmp_face_parts_list, dim=1))
|
||||
face_parts = torch.stack(face_parts_list, dim=2)
|
||||
|
||||
face_parts_tensor = rearrange(face_parts, "c f p h w -> (f p) c h w")
|
||||
face_parts_embedding_list = []
|
||||
with tqdm(total=face_parts_tensor.size(0)) as pbar:
|
||||
for i in range(0, face_parts_tensor.size(0)):
|
||||
face_parts_embedding = clip_encoder(face_parts_tensor[i:i+1].to(device=clip_encoder.device, dtype=clip_encoder.dtype)).image_embeds
|
||||
face_parts_embedding_list.append(face_parts_embedding.cpu())
|
||||
pbar.set_description('CLIP IMAGE ENCODER')
|
||||
pbar.update()
|
||||
def warp_face_pd_fgc(image, landmarks222, save_size=224):
|
||||
pt5_idx = [182, 202, 36, 149, 133]
|
||||
dst_pt5 = np.array([[0.3843, 0.27], [0.62, 0.2668], [0.503, 0.4185], [0.406, 0.5273], [0.5977, 0.525]]) * save_size
|
||||
src_pt5 = landmarks222[pt5_idx]
|
||||
|
||||
face_parts_embedding = torch.cat(face_parts_embedding_list, dim=0)
|
||||
face_parts_embedding = rearrange(face_parts_embedding,
|
||||
"(f p) c -> f p c",
|
||||
f=face_parts.size(2))
|
||||
return face_parts_embedding
|
||||
M = umeyama(src_pt5, dst_pt5, True)[0:2]
|
||||
warped = cv2.warpAffine(image, M, (save_size, save_size), flags=cv2.INTER_CUBIC)
|
||||
|
||||
def gen_control_heatmaps(drive_rot, drive_trans, ref_trans, save_size=512, trans_ratio=0.0):
|
||||
control_list = []
|
||||
for rot, trans in zip(drive_rot, drive_trans):
|
||||
rect = get_project_points_rect(rot, ref_trans + (trans - drive_trans[0]) * trans_ratio, save_size, save_size)
|
||||
control_heatmap = draw_skl_by_rect(save_size, rect)
|
||||
return warped
|
||||
|
||||
control_heatmap = image_preprocess(control_heatmap, (save_size, save_size))
|
||||
control_list.append(control_heatmap)
|
||||
return torch.stack(control_list, dim=1)
|
||||
|
||||
def det_landmarks(face_aligner, frame_list, save_size=(512, 512), reset=False):
|
||||
rect_list = []
|
||||
new_frame_list = []
|
||||
with tqdm(total=len(frame_list)) as pbar:
|
||||
for frame in frame_list:
|
||||
frame = cv2.resize(frame, save_size)
|
||||
faces = face_aligner.forward(frame, reset=reset)
|
||||
if len(faces) > 0:
|
||||
face = sorted(faces, key=lambda x: (x['face_rect'][2] - x['face_rect'][0]) * (
|
||||
x['face_rect'][3] - x['face_rect'][1]))[-1]
|
||||
rect_list.append(face['face_rect'])
|
||||
new_frame_list.append(frame)
|
||||
pbar.set_description('DET stage1')
|
||||
pbar.update()
|
||||
|
||||
face_aligner.reset_track()
|
||||
save_frame_list = []
|
||||
save_landmark_list = []
|
||||
with tqdm(total=len(new_frame_list)) as pbar:
|
||||
for frame, rect in zip(new_frame_list, rect_list):
|
||||
faces = face_aligner.forward(frame, pre_rect=rect, reset=reset)
|
||||
if len(faces) > 0:
|
||||
face = sorted(faces, key=lambda x: (x['face_rect'][2] - x['face_rect'][0]) * (
|
||||
x['face_rect'][3] - x['face_rect'][1]))[-1]
|
||||
landmarks = face['pre_kpt_222']
|
||||
save_frame_list.append(frame)
|
||||
save_landmark_list.append(landmarks)
|
||||
pbar.set_description('DET stage2')
|
||||
pbar.update()
|
||||
save_landmark_list = np.stack(save_landmark_list, axis=0).astype(np.float16)
|
||||
|
||||
face_aligner.reset_track()
|
||||
return save_frame_list, save_landmark_list
|
||||
|
||||
def get_drive_params(face_aligner, h3dmm, harkit_bs, frame_list, save_size, align=True):
|
||||
frame_num = len(frame_list)
|
||||
frame_list, landmark_list = det_landmarks(face_aligner, frame_list, save_size=(512, 512), reset=False)
|
||||
assert len(frame_list) == frame_num
|
||||
return get_face_params(h3dmm, harkit_bs, frame_list, landmark_list, save_size=save_size, align=align)
|
||||
|
||||
def crop_and_resize(frames, landmarks, save_size=512, crop=True):
|
||||
H, W = frames[0].shape[:2]
|
||||
@@ -307,6 +336,7 @@ def crop_and_resize(frames, landmarks, save_size=512, crop=True):
|
||||
frames = np.stack([cv2.resize(frame, (save_size, save_size), interpolation=cv2.INTER_CUBIC) for frame in frames], axis=0)
|
||||
return frames, landmarks
|
||||
|
||||
|
||||
def umeyama(src, dst, estimate_scale):
|
||||
"""Estimate N-D similarity transformation with or without scaling.
|
||||
Parameters
|
||||
@@ -377,6 +407,7 @@ def umeyama(src, dst, estimate_scale):
|
||||
|
||||
return T
|
||||
|
||||
|
||||
def ff_cat_video_and_audio(video_path, audio_path, output_path):
|
||||
cmd = [
|
||||
"ffmpeg",
|
||||
@@ -392,6 +423,7 @@ def ff_cat_video_and_audio(video_path, audio_path, output_path):
|
||||
]
|
||||
subprocess.run(cmd)
|
||||
|
||||
|
||||
def ff_change_fps(input_video, output_video, fps=15):
|
||||
cmd = [
|
||||
"ffmpeg",
|
||||
@@ -408,6 +440,7 @@ def ff_change_fps(input_video, output_video, fps=15):
|
||||
|
||||
subprocess.run(cmd)
|
||||
|
||||
|
||||
def load_data_list(data_dir, post_fix='.pickle;.txt'):
|
||||
post_fixs = post_fix.split(';')
|
||||
ret_list = []
|
||||
|
||||
@@ -1,4 +1,3 @@
|
||||
import os
|
||||
import os.path as osp
|
||||
import random
|
||||
|
||||
@@ -28,19 +27,23 @@ if missing:
|
||||
python = sys.executable
|
||||
subprocess.check_call([python, '-m', 'pip', 'install', *missing], stdout=subprocess.DEVNULL)
|
||||
|
||||
from .hellomeme.utils import (face_params_to_tensor,
|
||||
from .hellomeme.utils import (get_drive_expression,
|
||||
get_drive_expression_pd_fgc,
|
||||
gen_control_heatmaps,
|
||||
get_drive_params,
|
||||
get_drive_pose,
|
||||
crop_and_resize,
|
||||
get_face_params,
|
||||
det_landmarks,
|
||||
load_data_list,
|
||||
load_unet_from_safetensors
|
||||
)
|
||||
|
||||
from .hellomeme.tools import Hello3DMMPred, HelloARKitBSPred, HelloFaceAlignment, HelloCameraDemo
|
||||
from .hellomeme import HMImagePipeline, HMVideoPipeline, HMVideoSimplePipeline
|
||||
from .hellomeme.tools import Hello3DMMPred, HelloARKitBSPred, HelloFaceAlignment, HelloCameraDemo, FanEncoder
|
||||
from .hellomeme import HMImagePipeline, HMVideoPipeline
|
||||
from transformers import CLIPVisionModelWithProjection
|
||||
|
||||
DEFAULT_PROMPT = '(best quality), highly detailed, ultra-detailed, headshot, person, well-placed five sense organs, looking at the viewer, centered composition, sharp focus, realistic skin texture'
|
||||
|
||||
|
||||
class HMImagePipelineLoader:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
@@ -88,6 +91,7 @@ class HMImagePipelineLoader:
|
||||
|
||||
return (pipeline, )
|
||||
|
||||
|
||||
class HMVideoPipelineLoader:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
@@ -139,55 +143,6 @@ class HMVideoPipelineLoader:
|
||||
|
||||
return (pipeline,)
|
||||
|
||||
class HMVideoSimplePipelineLoader:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
checkpoint_files = sorted(load_data_list(osp.join(cur_dir, '../../models/checkpoints'), '.pt;.pth;.ckpt;.safetensors'))
|
||||
lora_files = sorted(load_data_list(osp.join(cur_dir, '../../models/loras'), '.safetensors'))
|
||||
|
||||
return {
|
||||
"optional": {
|
||||
"checkpoint_path": (['SD1.5'] + checkpoint_files, ),
|
||||
"lora_path": (['None'] + lora_files, ),
|
||||
"gpu_id": ("INT", {"default": 0}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("HMVIDEOPIPELINE",)
|
||||
RETURN_NAMES = ("hm_video_pipeline",)
|
||||
FUNCTION = "load_pipeline"
|
||||
CATEGORY = "hellomeme"
|
||||
|
||||
def load_pipeline(self, checkpoint_path=None, lora_path=None, gpu_id=0):
|
||||
dtype = torch.float16
|
||||
if gpu_id >= 0:
|
||||
device = torch.device("cuda:{}".format(gpu_id))
|
||||
else:
|
||||
device = torch.device("cpu")
|
||||
pipeline = HMVideoSimplePipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5").to(dtype=dtype,
|
||||
device=device)
|
||||
pipeline.caryomitosis()
|
||||
|
||||
### load customized checkpoint or lora here:
|
||||
## checkpoints
|
||||
|
||||
if checkpoint_path and osp.isfile(checkpoint_path):
|
||||
if checkpoint_path.endswith('.safetensors'):
|
||||
state_dict = load_unet_from_safetensors(checkpoint_path, pipeline.unet_ref.config)
|
||||
pipeline.unet.load_state_dict(state_dict, strict=False)
|
||||
elif osp.splitext(checkpoint_path)[-1] in ['.pt', '.pth', '.ckpt']:
|
||||
state_dict = torch.load(checkpoint_path)
|
||||
pipeline.unet.load_state_dict(state_dict, strict=False)
|
||||
else:
|
||||
print("Invalid checkpoint path", checkpoint_path)
|
||||
|
||||
### lora
|
||||
if lora_path and osp.isfile(lora_path):
|
||||
pipeline.load_lora_weights(osp.dirname(lora_path), weight_name=osp.basename(lora_path), adapter_name="lora")
|
||||
|
||||
pipeline.insert_hm_modules(dtype=dtype, device=device)
|
||||
|
||||
return (pipeline,)
|
||||
|
||||
class HMFaceToolkitsLoader:
|
||||
@classmethod
|
||||
@@ -204,45 +159,25 @@ class HMFaceToolkitsLoader:
|
||||
CATEGORY = "hellomeme"
|
||||
def load_face_toolkits(self, gpu_id):
|
||||
dtype = torch.float16
|
||||
device = torch.device(f'cuda:{gpu_id}')
|
||||
if gpu_id < 0:
|
||||
device = torch.device('cpu')
|
||||
else:
|
||||
device = torch.device(f'cuda:{gpu_id}')
|
||||
return (
|
||||
dict(
|
||||
device=device,
|
||||
dtype=dtype,
|
||||
pd_fpg_motion=FanEncoder.from_pretrained("songkey/pd_fgc_motion").to(dtype=dtype),
|
||||
face_aligner=HelloCameraDemo(face_alignment_module=HelloFaceAlignment(gpu_id=gpu_id), reset=False),
|
||||
harkit_bs=HelloARKitBSPred(gpu_id=gpu_id),
|
||||
h3dmm=Hello3DMMPred(gpu_id=gpu_id),
|
||||
image_encoder=CLIPVisionModelWithProjection.from_pretrained(
|
||||
'h94/IP-Adapter', subfolder='models/image_encoder').to(dtype=dtype)
|
||||
),
|
||||
)
|
||||
|
||||
face_aligner = HelloCameraDemo(face_alignment_module=HelloFaceAlignment(gpu_id=gpu_id), reset=True)
|
||||
harkit_bs = HelloARKitBSPred(gpu_id=gpu_id)
|
||||
h3dmm = Hello3DMMPred(gpu_id=gpu_id)
|
||||
clip_image_encoder = CLIPVisionModelWithProjection.from_pretrained(
|
||||
'h94/IP-Adapter',subfolder='models/image_encoder').to(dtype=dtype, device=device)
|
||||
return (dict(face_aligner=face_aligner, harkit_bs=harkit_bs, h3dmm=h3dmm, image_encoder=clip_image_encoder), )
|
||||
|
||||
class GetReferenceImageRT:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"face_toolkits": ("FACE_TOOLKITS",),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("REFRT",)
|
||||
RETURN_NAMES = ("ref_rt",)
|
||||
FUNCTION = "get_reference_image_rt"
|
||||
CATEGORY = "hellomeme"
|
||||
|
||||
def get_reference_image_rt(self, image, face_toolkits):
|
||||
image_np = cv2.cvtColor((image[0] * 255).cpu().numpy().astype(np.uint8), cv2.COLOR_BGR2RGB)
|
||||
image_np = cv2.resize(image_np, (512, 512))
|
||||
# print(image_np.shape)
|
||||
face_toolkits['face_aligner'].reset_track()
|
||||
faces = face_toolkits['face_aligner'].forward(image_np)
|
||||
assert len(faces) > 0
|
||||
face = sorted(faces, key=lambda x: (x['face_rect'][2] - x['face_rect'][0]) * (
|
||||
x['face_rect'][3] - x['face_rect'][1]))[-1]
|
||||
ref_landmark = face['pre_kpt_222']
|
||||
|
||||
ref_rot, ref_trans = face_toolkits['h3dmm'].forward_params(image_np, ref_landmark)
|
||||
return (dict(rot=ref_rot, trans=ref_trans), )
|
||||
|
||||
class CropReferenceImage:
|
||||
class CropPortrait:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
@@ -253,10 +188,10 @@ class CropReferenceImage:
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
FUNCTION = "crop_reference_image"
|
||||
FUNCTION = "crop_portrait"
|
||||
CATEGORY = "hellomeme"
|
||||
|
||||
def crop_reference_image(self, image, face_toolkits):
|
||||
def crop_portrait(self, image, face_toolkits):
|
||||
image_np = cv2.cvtColor((image[0] * 255).cpu().numpy().astype(np.uint8), cv2.COLOR_BGR2RGB)
|
||||
image_np = cv2.resize(image_np, (512, 512))
|
||||
# print(image_np.shape)
|
||||
@@ -271,50 +206,95 @@ class CropReferenceImage:
|
||||
new_image = cv2.cvtColor(new_image[0], cv2.COLOR_RGB2BGR)
|
||||
return (torch.from_numpy(new_image[np.newaxis, :,:,:]).float() / 255., )
|
||||
|
||||
class GetImageDriveParams:
|
||||
|
||||
class GetFaceLandmarks:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"face_toolkits": ("FACE_TOOLKITS",),
|
||||
"image": ("IMAGE",),
|
||||
"ref_rt": ("REFRT",),
|
||||
"images": ("IMAGE",),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("DRIVE_PARAMS",)
|
||||
RETURN_NAMES = ("drive_params",)
|
||||
FUNCTION = "get_face_params"
|
||||
RETURN_TYPES = ("FACELANDMARKS222",)
|
||||
RETURN_NAMES = ("landmarks",)
|
||||
FUNCTION = "get_face_landmarks"
|
||||
CATEGORY = "hellomeme"
|
||||
def get_face_params(self, face_toolkits, image, ref_rt):
|
||||
dtype = torch.float16
|
||||
|
||||
image_np = cv2.cvtColor((image[0] * 255).cpu().numpy().astype(np.uint8), cv2.COLOR_BGR2RGB)
|
||||
def get_face_landmarks(self, face_toolkits, images):
|
||||
frame_list = [cv2.cvtColor((frame * 255).cpu().numpy().astype(np.uint8), cv2.COLOR_BGR2RGB) for frame in images]
|
||||
frame_num = len(frame_list)
|
||||
assert frame_num > 0
|
||||
_, landmark_list = det_landmarks(face_toolkits['face_aligner'], frame_list)
|
||||
assert len(frame_list) == frame_num
|
||||
|
||||
face_toolkits['face_aligner'].reset_track()
|
||||
faces = face_toolkits['face_aligner'].forward(image_np)
|
||||
assert len(faces) > 0
|
||||
return (torch.from_numpy(landmark_list).float(), )
|
||||
|
||||
face = sorted(faces, key=lambda x: (x['face_rect'][2] - x['face_rect'][0]) * (
|
||||
x['face_rect'][3] - x['face_rect'][1]))[-1]
|
||||
drive_landmark = face['pre_kpt_222']
|
||||
|
||||
drive_face_parts, drive_coeff, drive_rot, drive_trans = get_face_params(face_toolkits['h3dmm'],
|
||||
face_toolkits['harkit_bs'],
|
||||
[image_np],
|
||||
[drive_landmark],
|
||||
save_size=(512, 512),
|
||||
align=False)
|
||||
class GetDrivePose:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"face_toolkits": ("FACE_TOOLKITS",),
|
||||
"images": ("IMAGE",),
|
||||
"landmarks": ("FACELANDMARKS222",),
|
||||
}
|
||||
}
|
||||
RETURN_TYPES = ("DRIVE_POSE",)
|
||||
RETURN_NAMES = ("drive_pose",)
|
||||
FUNCTION = "get_drive_pose"
|
||||
CATEGORY = "hellomeme"
|
||||
def get_drive_pose(self, face_toolkits, images, landmarks):
|
||||
frame_list = [cv2.cvtColor((frame * 255).cpu().numpy().astype(np.uint8), cv2.COLOR_BGR2RGB) for frame in images]
|
||||
landmarks = landmarks.cpu().numpy()
|
||||
|
||||
face_parts_embedding = face_params_to_tensor(face_toolkits['image_encoder'], drive_face_parts)
|
||||
rot_list, trans_list = get_drive_pose(face_toolkits, frame_list, landmarks, save_size=512)
|
||||
return (dict(rot=np.stack(rot_list), trans=np.stack(trans_list)), )
|
||||
|
||||
|
||||
class GetDriveExpression:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"face_toolkits": ("FACE_TOOLKITS",),
|
||||
"images": ("IMAGE",),
|
||||
"landmarks": ("FACELANDMARKS222",),
|
||||
}
|
||||
}
|
||||
RETURN_TYPES = ("DRIVE_EXPRESSION",)
|
||||
RETURN_NAMES = ("drive_exp",)
|
||||
FUNCTION = "get_drive_expression"
|
||||
CATEGORY = "hellomeme"
|
||||
def get_drive_expression(self, face_toolkits, images, landmarks):
|
||||
frame_list = [cv2.cvtColor((frame * 255).cpu().numpy().astype(np.uint8), cv2.COLOR_BGR2RGB) for frame in images]
|
||||
landmarks = landmarks.cpu().numpy()
|
||||
exp_dict = get_drive_expression(face_toolkits, frame_list, landmarks)
|
||||
return (exp_dict, )
|
||||
|
||||
|
||||
class GetDriveExpression2:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"face_toolkits": ("FACE_TOOLKITS",),
|
||||
"images": ("IMAGE",),
|
||||
"landmarks": ("FACELANDMARKS222",),
|
||||
}
|
||||
}
|
||||
RETURN_TYPES = ("DRIVE_EXPRESSION2",)
|
||||
RETURN_NAMES = ("drive_exp2",)
|
||||
FUNCTION = "get_drive_expression"
|
||||
CATEGORY = "hellomeme"
|
||||
def get_drive_expression(self, face_toolkits, images, landmarks):
|
||||
frame_list = [cv2.cvtColor((frame * 255).cpu().numpy().astype(np.uint8), cv2.COLOR_BGR2RGB) for frame in images]
|
||||
landmarks = landmarks.cpu().numpy()
|
||||
exp_dict = get_drive_expression_pd_fgc(face_toolkits, frame_list, landmarks)
|
||||
return (exp_dict, )
|
||||
|
||||
drive_params = dict(
|
||||
face_parts=face_parts_embedding.unsqueeze(0).to(dtype=dtype, device='cpu'),
|
||||
drive_coeff=drive_coeff.unsqueeze(0).to(dtype=dtype, device='cpu'),
|
||||
drive_rot=drive_rot,
|
||||
drive_trans=drive_trans,
|
||||
)
|
||||
return (drive_params, )
|
||||
|
||||
class HMPipelineImage:
|
||||
@classmethod
|
||||
@@ -322,32 +302,61 @@ class HMPipelineImage:
|
||||
return {
|
||||
"required": {
|
||||
"hm_image_pipeline": ("HMIMAGEPIPELINE",),
|
||||
"face_toolkits": ("FACE_TOOLKITS",),
|
||||
"ref_image": ("IMAGE",),
|
||||
"ref_rt": ("REFRT",),
|
||||
"drive_pose": ("DRIVE_POSE",),
|
||||
"trans_ratio": ("FLOAT", {"default": 0.0, "min": 0.0, "max": 1.0, "step": 0.01}),
|
||||
"drive_params": ("DRIVE_PARAMS",),
|
||||
"prompt": ("STRING", {"default": '(best quality), highly detailed, ultra-detailed, headshot, person, well-placed five sense organs, looking at the viewer, centered composition, sharp focus, realistic skin texture'}),
|
||||
"prompt": ("STRING", {"default": DEFAULT_PROMPT}),
|
||||
"negative_prompt": ("STRING", {"default": ''}),
|
||||
"steps": ("INT", {"default": 25, "min": 1, "max": 1000}),
|
||||
"seed": ("INT", {"default": -1, "min": -1, "max": 100000}),
|
||||
"guidance_scale": ("FLOAT", {"default": 2.0, "min": 0.0, "max": 100.0, "step": 0.01}),
|
||||
}
|
||||
},
|
||||
"optional": {
|
||||
"drive_exp": ("DRIVE_EXPRESSION", {"default": None},),
|
||||
"drive_exp2": ("DRIVE_EXPRESSION2", {"default": None},),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
FUNCTION = "sample"
|
||||
CATEGORY = "hellomeme"
|
||||
|
||||
def sample(self, hm_image_pipeline, ref_image, ref_rt, trans_ratio, drive_params, prompt, negative_prompt, steps=25, seed=-1, guidance_scale=2.0):
|
||||
def sample(self,
|
||||
hm_image_pipeline,
|
||||
face_toolkits,
|
||||
ref_image,
|
||||
drive_pose,
|
||||
drive_exp=None,
|
||||
drive_exp2=None,
|
||||
trans_ratio='0.0',
|
||||
prompt=DEFAULT_PROMPT,
|
||||
negative_prompt='',
|
||||
steps=25,
|
||||
seed=-1,
|
||||
guidance_scale=2.0
|
||||
):
|
||||
image_np = (ref_image[0] * 255).cpu().numpy().astype(np.uint8)
|
||||
image_np = cv2.resize(image_np, (512, 512))
|
||||
image_pil = Image.fromarray(image_np)
|
||||
|
||||
drive_rot = drive_params['drive_rot']
|
||||
drive_trans = drive_params['drive_trans']
|
||||
face_toolkits['face_aligner'].reset_track()
|
||||
faces = face_toolkits['face_aligner'].forward(image_np)
|
||||
assert len(faces) > 0
|
||||
face = sorted(faces, key=lambda x: (x['face_rect'][2] - x['face_rect'][0]) * (
|
||||
x['face_rect'][3] - x['face_rect'][1]))[-1]
|
||||
ref_landmark = face['pre_kpt_222']
|
||||
|
||||
condition = gen_control_heatmaps(drive_rot, drive_trans, ref_rt['trans'], 512, trans_ratio)
|
||||
drive_params['condition'] = condition.unsqueeze(0).to(dtype=torch.float16, device='cpu')
|
||||
_, ref_trans = face_toolkits['h3dmm'].forward_params(image_np, ref_landmark)
|
||||
|
||||
drive_rot, drive_trans = drive_pose['rot'], drive_pose['trans']
|
||||
condition = gen_control_heatmaps(drive_rot, drive_trans, ref_trans, 512, trans_ratio)
|
||||
drive_params = dict(condition=condition.unsqueeze(0).to(dtype=torch.float16, device='cpu'))
|
||||
|
||||
if isinstance(drive_exp, dict):
|
||||
drive_params.update(drive_exp)
|
||||
if isinstance(drive_exp2, dict):
|
||||
drive_params.update(drive_exp2)
|
||||
|
||||
if seed < 0:
|
||||
generator = torch.Generator().manual_seed(random.randint(0, 100000))
|
||||
@@ -367,83 +376,82 @@ class HMPipelineImage:
|
||||
)
|
||||
return (torch.from_numpy(np.clip(result_img[0], 0, 1)), )
|
||||
|
||||
class GetVideoDriveParams:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"face_toolkits": ("FACE_TOOLKITS",),
|
||||
"images": ("IMAGE",),
|
||||
}
|
||||
}
|
||||
RETURN_TYPES = ("DRIVE_PARAMS",)
|
||||
RETURN_NAMES = ("drive_params",)
|
||||
FUNCTION = "get_face_params"
|
||||
CATEGORY = "hellomeme"
|
||||
def get_face_params(self, face_toolkits, images):
|
||||
dtype = torch.float16
|
||||
|
||||
frame_list = [cv2.cvtColor((frame * 255).cpu().numpy().astype(np.uint8), cv2.COLOR_BGR2RGB) for frame in images]
|
||||
|
||||
face_toolkits['face_aligner'].reset_track()
|
||||
(drive_face_parts, drive_coeff, drive_rot, drive_trans) = get_drive_params(face_toolkits['face_aligner'],
|
||||
face_toolkits['h3dmm'],
|
||||
face_toolkits['harkit_bs'],
|
||||
frame_list=frame_list,
|
||||
save_size=512,
|
||||
align=True)
|
||||
face_toolkits['face_aligner'].reset_track()
|
||||
face_parts_embedding = face_params_to_tensor(face_toolkits['image_encoder'], drive_face_parts)
|
||||
|
||||
drive_params = dict(
|
||||
face_parts=face_parts_embedding.unsqueeze(0).to(dtype=dtype, device='cpu'),
|
||||
drive_coeff=drive_coeff.unsqueeze(0).to(dtype=dtype, device='cpu'),
|
||||
drive_rot=drive_rot,
|
||||
drive_trans=drive_trans,
|
||||
)
|
||||
return (drive_params, )
|
||||
|
||||
class HMPipelineVideo:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {"required":
|
||||
{
|
||||
return {
|
||||
"required":{
|
||||
"hm_video_pipeline": ("HMVIDEOPIPELINE",),
|
||||
"face_toolkits": ("FACE_TOOLKITS",),
|
||||
"ref_image": ("IMAGE",),
|
||||
"ref_rt": ("REFRT",),
|
||||
"drive_pose": ("DRIVE_POSE",),
|
||||
"trans_ratio": ("FLOAT", {"default": 0.0, "min": 0.0, "max": 1.0, "step": 0.01}),
|
||||
"drive_params": ("DRIVE_PARAMS",),
|
||||
"prompt": ("STRING", {"default": '(best quality), highly detailed, ultra-detailed, headshot, person, well-placed five sense organs, looking at the viewer, centered composition, sharp focus, realistic skin texture'}),
|
||||
"patch_overlap": ("INT", {"default": 4, "min": 0, "max": 5}),
|
||||
"prompt": ("STRING", {"default": DEFAULT_PROMPT}),
|
||||
"negative_prompt": ("STRING", {"default": ''}),
|
||||
"steps": ("INT", {"default": 25, "min": 1, "max": 1000}),
|
||||
"seed": ("INT", {"default": -1, "min": -1, "max": 100000}),
|
||||
"guidance_scale": ("FLOAT", {"default": 2.0, "min": 0.0, "max": 100.0, "step": 0.01}),
|
||||
}
|
||||
},
|
||||
"optional": {
|
||||
"drive_exp": ("DRIVE_EXPRESSION", {"default": None},),
|
||||
"drive_exp2": ("DRIVE_EXPRESSION2", {"default": None},),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
FUNCTION = "sample"
|
||||
CATEGORY = "hellomeme"
|
||||
|
||||
def sample(self, hm_video_pipeline, ref_image, ref_rt, trans_ratio, drive_params, prompt, negative_prompt, steps=25, seed=-1, guidance_scale=2.0):
|
||||
def sample(self,
|
||||
hm_video_pipeline,
|
||||
face_toolkits,
|
||||
ref_image,
|
||||
drive_pose,
|
||||
drive_exp=None,
|
||||
drive_exp2=None,
|
||||
trans_ratio=0.0,
|
||||
patch_overlap=4,
|
||||
prompt=DEFAULT_PROMPT,
|
||||
negative_prompt="",
|
||||
steps=25,
|
||||
seed=-1,
|
||||
guidance_scale=2.0
|
||||
):
|
||||
image_np = (ref_image[0] * 255).cpu().numpy().astype(np.uint8)
|
||||
image_np = cv2.resize(image_np, (512, 512))
|
||||
image_pil = Image.fromarray(image_np)
|
||||
|
||||
face_toolkits['face_aligner'].reset_track()
|
||||
faces = face_toolkits['face_aligner'].forward(image_np)
|
||||
face_toolkits['face_aligner'].reset_track()
|
||||
assert len(faces) > 0
|
||||
face = sorted(faces, key=lambda x: (x['face_rect'][2] - x['face_rect'][0]) * (
|
||||
x['face_rect'][3] - x['face_rect'][1]))[-1]
|
||||
ref_landmark = face['pre_kpt_222']
|
||||
|
||||
_, ref_trans = face_toolkits['h3dmm'].forward_params(image_np, ref_landmark)
|
||||
|
||||
if seed < 0:
|
||||
generator = torch.Generator().manual_seed(random.randint(0, 100000))
|
||||
else:
|
||||
generator = torch.Generator().manual_seed(seed)
|
||||
|
||||
drive_rot = drive_params['drive_rot']
|
||||
drive_trans = drive_params['drive_trans']
|
||||
drive_rot, drive_trans = drive_pose['rot'], drive_pose['trans']
|
||||
condition = gen_control_heatmaps(drive_rot, drive_trans, ref_trans, 512, trans_ratio)
|
||||
drive_params = dict(condition=condition.unsqueeze(0).to(dtype=torch.float16, device='cpu'))
|
||||
|
||||
condition = gen_control_heatmaps(drive_rot, drive_trans, ref_rt['trans'], 512, trans_ratio)
|
||||
drive_params['condition'] = condition.unsqueeze(0).to(dtype=torch.float16, device='cpu')
|
||||
if isinstance(drive_exp, dict):
|
||||
drive_params.update(drive_exp)
|
||||
if isinstance(drive_exp2, dict):
|
||||
drive_params.update(drive_exp2)
|
||||
|
||||
res_frames = hm_video_pipeline(
|
||||
prompt=[prompt],
|
||||
strength=1.0,
|
||||
image=image_pil,
|
||||
chunk_overlap=patch_overlap,
|
||||
drive_params=drive_params,
|
||||
num_inference_steps=steps,
|
||||
negative_prompt=[negative_prompt],
|
||||
@@ -454,28 +462,29 @@ class HMPipelineVideo:
|
||||
res_frames = [np.clip(x[0], 0, 1) for x in res_frames]
|
||||
return (torch.from_numpy(np.array(res_frames)), )
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"HMImagePipelineLoader": HMImagePipelineLoader,
|
||||
"HMVideoPipelineLoader": HMVideoPipelineLoader,
|
||||
"HMVideoSimplePipelineLoader": HMVideoSimplePipelineLoader,
|
||||
"HMFaceToolkitsLoader": HMFaceToolkitsLoader,
|
||||
"GetReferenceImageRT": GetReferenceImageRT,
|
||||
"GetImageDriveParams": GetImageDriveParams,
|
||||
"GetVideoDriveParams": GetVideoDriveParams,
|
||||
"HMPipelineImage": HMPipelineImage,
|
||||
"HMPipelineVideo": HMPipelineVideo,
|
||||
"CropReferenceImage": CropReferenceImage,
|
||||
"CropPortrait": CropPortrait,
|
||||
"GetFaceLandmarks": GetFaceLandmarks,
|
||||
"GetDrivePose": GetDrivePose,
|
||||
"GetDriveExpression": GetDriveExpression,
|
||||
"GetDriveExpression2": GetDriveExpression2,
|
||||
}
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"HMImagePipelineLoader": "Load HelloMemeImage Pipeline",
|
||||
"HMVideoPipelineLoader": "Load HelloMemeVideo Pipeline",
|
||||
"HMVideoSimplePipelineLoader": "Load HelloMemeVideoSimple Pipeline",
|
||||
"HMFaceToolkitsLoader": "Load Face Toolkits",
|
||||
"GetReferenceImageT": "Get Reference Image Translation",
|
||||
"GetImageDriveParams": "Get Drive Image Parameters",
|
||||
"GetVideoDriveParams": "Get Drive Video Parameters",
|
||||
"HMPipelineImage": "HelloMeme Image Pipeline",
|
||||
"HMPipelineVideo": "HelloMeme Video Pipeline",
|
||||
"CropReferenceImage": "Crop Reference Image",
|
||||
"CropPortrait": "Crop Portrait",
|
||||
"GetFaceLandmarks": "Get Face Landmarks",
|
||||
"GetDrivePose": "Get Drive Pose",
|
||||
"GetDriveExpression": "Get Drive Expression",
|
||||
"GetDriveExpression2": "Get Drive Expression V2",
|
||||
}
|
||||
|
||||

Binary file not shown.
|
Before Width: | Height: | Size: 221 KiB |

Binary file not shown.
|
After Width: | Height: | Size: 630 KiB |
@@ -0,0 +1,567 @@
|
||||
{
|
||||
"last_node_id": 60,
|
||||
"last_link_id": 123,
|
||||
"nodes": [
|
||||
{
|
||||
"id": 8,
|
||||
"type": "LoadImage",
|
||||
"pos": {
|
||||
"0": 24,
|
||||
"1": 133
|
||||
},
|
||||
"size": {
|
||||
"0": 426.5283508300781,
|
||||
"1": 476.4518127441406
|
||||
},
|
||||
"flags": {},
|
||||
"order": 0,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
56
|
||||
],
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "MASK",
|
||||
"type": "MASK",
|
||||
"links": null
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadImage"
|
||||
},
|
||||
"widgets_values": [
|
||||
"majicmix2.jpg",
|
||||
"image"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 43,
|
||||
"type": "GetFaceLandmarks",
|
||||
"pos": {
|
||||
"0": 465,
|
||||
"1": 771
|
||||
},
|
||||
"size": {
|
||||
"0": 292.20001220703125,
|
||||
"1": 46
|
||||
},
|
||||
"flags": {},
|
||||
"order": 5,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 62
|
||||
},
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 115
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "landmarks",
|
||||
"type": "FACELANDMARKS222",
|
||||
"links": [
|
||||
64,
|
||||
112
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "GetFaceLandmarks"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 57,
|
||||
"type": "LoadImage",
|
||||
"pos": {
|
||||
"0": 45,
|
||||
"1": 867
|
||||
},
|
||||
"size": [
|
||||
315,
|
||||
314
|
||||
],
|
||||
"flags": {},
|
||||
"order": 1,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
115,
|
||||
116,
|
||||
117
|
||||
],
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "MASK",
|
||||
"type": "MASK",
|
||||
"links": null
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadImage"
|
||||
},
|
||||
"widgets_values": [
|
||||
"yao.jpg",
|
||||
"image"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 39,
|
||||
"type": "CropPortrait",
|
||||
"pos": {
|
||||
"0": 516,
|
||||
"1": 537
|
||||
},
|
||||
"size": {
|
||||
"0": 241.79998779296875,
|
||||
"1": 46
|
||||
},
|
||||
"flags": {},
|
||||
"order": 4,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "image",
|
||||
"type": "IMAGE",
|
||||
"link": 56
|
||||
},
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 57
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
118
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "CropPortrait"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 2,
|
||||
"type": "HMFaceToolkitsLoader",
|
||||
"pos": {
|
||||
"0": 43,
|
||||
"1": 699
|
||||
},
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 58
|
||||
},
|
||||
"flags": {},
|
||||
"order": 2,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"links": [
|
||||
57,
|
||||
62,
|
||||
65,
|
||||
114,
|
||||
119
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "HMFaceToolkitsLoader"
|
||||
},
|
||||
"widgets_values": [
|
||||
0
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 44,
|
||||
"type": "GetDrivePose",
|
||||
"pos": {
|
||||
"0": 852,
|
||||
"1": 661
|
||||
},
|
||||
"size": {
|
||||
"0": 304.79998779296875,
|
||||
"1": 66
|
||||
},
|
||||
"flags": {},
|
||||
"order": 6,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 65
|
||||
},
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 116
|
||||
},
|
||||
{
|
||||
"name": "landmarks",
|
||||
"type": "FACELANDMARKS222",
|
||||
"link": 64
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "drive_pose",
|
||||
"type": "DRIVE_POSE",
|
||||
"links": [
|
||||
120
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "GetDrivePose"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 58,
|
||||
"type": "HMPipelineImage",
|
||||
"pos": {
|
||||
"0": 1274,
|
||||
"1": 584
|
||||
},
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 302
|
||||
},
|
||||
"flags": {},
|
||||
"order": 8,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "hm_image_pipeline",
|
||||
"type": "HMIMAGEPIPELINE",
|
||||
"link": 123
|
||||
},
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 119
|
||||
},
|
||||
{
|
||||
"name": "ref_image",
|
||||
"type": "IMAGE",
|
||||
"link": 118
|
||||
},
|
||||
{
|
||||
"name": "drive_pose",
|
||||
"type": "DRIVE_POSE",
|
||||
"link": 120
|
||||
},
|
||||
{
|
||||
"name": "drive_exp",
|
||||
"type": "DRIVE_EXPRESSION",
|
||||
"link": null,
|
||||
"shape": 7
|
||||
},
|
||||
{
|
||||
"name": "drive_exp2",
|
||||
"type": "DRIVE_EXPRESSION2",
|
||||
"link": 121,
|
||||
"shape": 7
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
122
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "HMPipelineImage"
|
||||
},
|
||||
"widgets_values": [
|
||||
0,
|
||||
"(best quality), highly detailed, ultra-detailed, headshot, person, well-placed five sense organs, looking at the viewer, centered composition, sharp focus, realistic skin texture",
|
||||
"",
|
||||
25,
|
||||
55468,
|
||||
"randomize",
|
||||
2
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 60,
|
||||
"type": "HMImagePipelineLoader",
|
||||
"pos": {
|
||||
"0": 815,
|
||||
"1": 390
|
||||
},
|
||||
"size": {
|
||||
"0": 352.79998779296875,
|
||||
"1": 106
|
||||
},
|
||||
"flags": {},
|
||||
"order": 3,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "hm_image_pipeline",
|
||||
"type": "HMIMAGEPIPELINE",
|
||||
"links": [
|
||||
123
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "HMImagePipelineLoader"
|
||||
},
|
||||
"widgets_values": [
|
||||
"SD1.5",
|
||||
"None",
|
||||
0
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 59,
|
||||
"type": "PreviewImage",
|
||||
"pos": {
|
||||
"0": 1688,
|
||||
"1": 584
|
||||
},
|
||||
"size": [
|
||||
210,
|
||||
246
|
||||
],
|
||||
"flags": {},
|
||||
"order": 9,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 122
|
||||
}
|
||||
],
|
||||
"outputs": [],
|
||||
"properties": {
|
||||
"Node name for S&R": "PreviewImage"
|
||||
}
|
||||
},
|
||||
{
|
||||
"id": 56,
|
||||
"type": "GetDriveExpression2",
|
||||
"pos": {
|
||||
"0": 852,
|
||||
"1": 806
|
||||
},
|
||||
"size": {
|
||||
"0": 304.79998779296875,
|
||||
"1": 66
|
||||
},
|
||||
"flags": {},
|
||||
"order": 7,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 114
|
||||
},
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 117
|
||||
},
|
||||
{
|
||||
"name": "landmarks",
|
||||
"type": "FACELANDMARKS222",
|
||||
"link": 112
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "drive_exp2",
|
||||
"type": "DRIVE_EXPRESSION2",
|
||||
"links": [
|
||||
121
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "GetDriveExpression2"
|
||||
}
|
||||
}
|
||||
],
|
||||
"links": [
|
||||
[
|
||||
56,
|
||||
8,
|
||||
0,
|
||||
39,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
57,
|
||||
2,
|
||||
0,
|
||||
39,
|
||||
1,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
62,
|
||||
2,
|
||||
0,
|
||||
43,
|
||||
0,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
64,
|
||||
43,
|
||||
0,
|
||||
44,
|
||||
2,
|
||||
"FACELANDMARKS222"
|
||||
],
|
||||
[
|
||||
65,
|
||||
2,
|
||||
0,
|
||||
44,
|
||||
0,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
112,
|
||||
43,
|
||||
0,
|
||||
56,
|
||||
2,
|
||||
"FACELANDMARKS222"
|
||||
],
|
||||
[
|
||||
114,
|
||||
2,
|
||||
0,
|
||||
56,
|
||||
0,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
115,
|
||||
57,
|
||||
0,
|
||||
43,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
116,
|
||||
57,
|
||||
0,
|
||||
44,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
117,
|
||||
57,
|
||||
0,
|
||||
56,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
118,
|
||||
39,
|
||||
0,
|
||||
58,
|
||||
2,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
119,
|
||||
2,
|
||||
0,
|
||||
58,
|
||||
1,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
120,
|
||||
44,
|
||||
0,
|
||||
58,
|
||||
3,
|
||||
"DRIVE_POSE"
|
||||
],
|
||||
[
|
||||
121,
|
||||
56,
|
||||
0,
|
||||
58,
|
||||
5,
|
||||
"DRIVE_EXPRESSION2"
|
||||
],
|
||||
[
|
||||
122,
|
||||
58,
|
||||
0,
|
||||
59,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
123,
|
||||
60,
|
||||
0,
|
||||
58,
|
||||
0,
|
||||
"HMIMAGEPIPELINE"
|
||||
]
|
||||
],
|
||||
"groups": [],
|
||||
"config": {},
|
||||
"extra": {
|
||||
"ds": {
|
||||
"scale": 0.7513148009015777,
|
||||
"offset": [
|
||||
328.1068082440709,
|
||||
3.5829604274896685
|
||||
]
|
||||
}
|
||||
},
|
||||
"version": 0.4
|
||||
}
|
||||
@@ -1,44 +1,17 @@
|
||||
{
|
||||
"last_node_id": 38,
|
||||
"last_link_id": 58,
|
||||
"last_node_id": 61,
|
||||
"last_link_id": 127,
|
||||
"nodes": [
|
||||
{
|
||||
"id": 26,
|
||||
"type": "PreviewImage",
|
||||
"pos": {
|
||||
"0": 795,
|
||||
"1": 121
|
||||
},
|
||||
"size": {
|
||||
"0": 210,
|
||||
"1": 246
|
||||
},
|
||||
"flags": {},
|
||||
"order": 6,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 34
|
||||
}
|
||||
],
|
||||
"outputs": [],
|
||||
"properties": {
|
||||
"Node name for S&R": "PreviewImage"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 8,
|
||||
"type": "LoadImage",
|
||||
"pos": {
|
||||
"0": 61,
|
||||
"1": 290
|
||||
"0": 24,
|
||||
"1": 133
|
||||
},
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 314
|
||||
"0": 426.5283508300781,
|
||||
"1": 476.4518127441406
|
||||
},
|
||||
"flags": {},
|
||||
"order": 0,
|
||||
@@ -49,7 +22,7 @@
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
31
|
||||
56
|
||||
],
|
||||
"slot_index": 0
|
||||
},
|
||||
@@ -68,18 +41,236 @@
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 36,
|
||||
"id": 39,
|
||||
"type": "CropPortrait",
|
||||
"pos": {
|
||||
"0": 516,
|
||||
"1": 537
|
||||
},
|
||||
"size": {
|
||||
"0": 241.79998779296875,
|
||||
"1": 46
|
||||
},
|
||||
"flags": {},
|
||||
"order": 4,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "image",
|
||||
"type": "IMAGE",
|
||||
"link": 56
|
||||
},
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 57
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
118
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "CropPortrait"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 44,
|
||||
"type": "GetDrivePose",
|
||||
"pos": {
|
||||
"0": 852,
|
||||
"1": 661
|
||||
},
|
||||
"size": {
|
||||
"0": 304.79998779296875,
|
||||
"1": 66
|
||||
},
|
||||
"flags": {},
|
||||
"order": 6,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 65
|
||||
},
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 116
|
||||
},
|
||||
{
|
||||
"name": "landmarks",
|
||||
"type": "FACELANDMARKS222",
|
||||
"link": 64
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "drive_pose",
|
||||
"type": "DRIVE_POSE",
|
||||
"links": [
|
||||
120
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "GetDrivePose"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 58,
|
||||
"type": "HMPipelineImage",
|
||||
"pos": {
|
||||
"0": 1274,
|
||||
"1": 584
|
||||
},
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 302
|
||||
},
|
||||
"flags": {},
|
||||
"order": 8,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "hm_image_pipeline",
|
||||
"type": "HMIMAGEPIPELINE",
|
||||
"link": 123
|
||||
},
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 119
|
||||
},
|
||||
{
|
||||
"name": "ref_image",
|
||||
"type": "IMAGE",
|
||||
"link": 118
|
||||
},
|
||||
{
|
||||
"name": "drive_pose",
|
||||
"type": "DRIVE_POSE",
|
||||
"link": 120
|
||||
},
|
||||
{
|
||||
"name": "drive_exp",
|
||||
"type": "DRIVE_EXPRESSION",
|
||||
"link": 124,
|
||||
"shape": 7
|
||||
},
|
||||
{
|
||||
"name": "drive_exp2",
|
||||
"type": "DRIVE_EXPRESSION2",
|
||||
"link": null,
|
||||
"shape": 7
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
122
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "HMPipelineImage"
|
||||
},
|
||||
"widgets_values": [
|
||||
0,
|
||||
"(best quality), highly detailed, ultra-detailed, headshot, person, well-placed five sense organs, looking at the viewer, centered composition, sharp focus, realistic skin texture",
|
||||
"",
|
||||
25,
|
||||
63934,
|
||||
"randomize",
|
||||
2
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 60,
|
||||
"type": "HMImagePipelineLoader",
|
||||
"pos": {
|
||||
"0": 815,
|
||||
"1": 390
|
||||
},
|
||||
"size": {
|
||||
"0": 352.79998779296875,
|
||||
"1": 106
|
||||
},
|
||||
"flags": {},
|
||||
"order": 1,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "hm_image_pipeline",
|
||||
"type": "HMIMAGEPIPELINE",
|
||||
"links": [
|
||||
123
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "HMImagePipelineLoader"
|
||||
},
|
||||
"widgets_values": [
|
||||
"SD1.5",
|
||||
"None",
|
||||
0
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 59,
|
||||
"type": "PreviewImage",
|
||||
"pos": {
|
||||
"0": 1688,
|
||||
"1": 584
|
||||
},
|
||||
"size": [
|
||||
210,
|
||||
246
|
||||
],
|
||||
"flags": {},
|
||||
"order": 9,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 122
|
||||
}
|
||||
],
|
||||
"outputs": [],
|
||||
"properties": {
|
||||
"Node name for S&R": "PreviewImage"
|
||||
}
|
||||
},
|
||||
{
|
||||
"id": 57,
|
||||
"type": "LoadImage",
|
||||
"pos": {
|
||||
"0": 65,
|
||||
"1": 871
|
||||
"0": 45,
|
||||
"1": 867
|
||||
},
|
||||
"size": [
|
||||
315,
|
||||
314
|
||||
],
|
||||
"flags": {},
|
||||
"order": 1,
|
||||
"order": 2,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
@@ -87,7 +278,9 @@
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
53
|
||||
115,
|
||||
116,
|
||||
125
|
||||
],
|
||||
"slot_index": 0
|
||||
},
|
||||
@@ -106,79 +299,44 @@
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 35,
|
||||
"type": "HMImagePipelineLoader",
|
||||
"id": 43,
|
||||
"type": "GetFaceLandmarks",
|
||||
"pos": {
|
||||
"0": 65,
|
||||
"1": 106
|
||||
"0": 465,
|
||||
"1": 771
|
||||
},
|
||||
"size": {
|
||||
"0": 352.79998779296875,
|
||||
"1": 106
|
||||
},
|
||||
"flags": {},
|
||||
"order": 2,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "hm_image_pipeline",
|
||||
"type": "HMIMAGEPIPELINE",
|
||||
"links": [
|
||||
54
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "HMImagePipelineLoader"
|
||||
},
|
||||
"widgets_values": [
|
||||
"SD1.5",
|
||||
"None",
|
||||
0
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 25,
|
||||
"type": "CropReferenceImage",
|
||||
"pos": {
|
||||
"0": 447,
|
||||
"1": 498
|
||||
},
|
||||
"size": {
|
||||
"0": 252,
|
||||
"0": 292.20001220703125,
|
||||
"1": 46
|
||||
},
|
||||
"flags": {},
|
||||
"order": 4,
|
||||
"order": 5,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "image",
|
||||
"type": "IMAGE",
|
||||
"link": 31
|
||||
},
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 32
|
||||
"link": 62
|
||||
},
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 115
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"name": "landmarks",
|
||||
"type": "FACELANDMARKS222",
|
||||
"links": [
|
||||
34,
|
||||
50,
|
||||
55
|
||||
64,
|
||||
126
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "CropReferenceImage"
|
||||
"Node name for S&R": "GetFaceLandmarks"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
@@ -186,8 +344,8 @@
|
||||
"id": 2,
|
||||
"type": "HMFaceToolkitsLoader",
|
||||
"pos": {
|
||||
"0": 61,
|
||||
"1": 697
|
||||
"0": 43,
|
||||
"1": 699
|
||||
},
|
||||
"size": {
|
||||
"0": 315,
|
||||
@@ -202,9 +360,11 @@
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"links": [
|
||||
32,
|
||||
42,
|
||||
51
|
||||
57,
|
||||
62,
|
||||
65,
|
||||
119,
|
||||
127
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
@@ -217,279 +377,189 @@
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 11,
|
||||
"type": "GetReferenceImageRT",
|
||||
"id": 61,
|
||||
"type": "GetDriveExpression",
|
||||
"pos": {
|
||||
"0": 749,
|
||||
"1": 546
|
||||
"0": 857,
|
||||
"1": 823
|
||||
},
|
||||
"size": {
|
||||
"0": 241.79998779296875,
|
||||
"1": 46
|
||||
"0": 292.20001220703125,
|
||||
"1": 66
|
||||
},
|
||||
"flags": {},
|
||||
"order": 7,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "image",
|
||||
"type": "IMAGE",
|
||||
"link": 50
|
||||
},
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 51
|
||||
"link": 127
|
||||
},
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 125
|
||||
},
|
||||
{
|
||||
"name": "landmarks",
|
||||
"type": "FACELANDMARKS222",
|
||||
"link": 126
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "ref_rt",
|
||||
"type": "REFRT",
|
||||
"name": "drive_exp",
|
||||
"type": "DRIVE_EXPRESSION",
|
||||
"links": [
|
||||
56
|
||||
124
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "GetReferenceImageRT"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 31,
|
||||
"type": "GetVideoDriveParams",
|
||||
"pos": {
|
||||
"0": 447,
|
||||
"1": 745
|
||||
},
|
||||
"size": {
|
||||
"0": 330,
|
||||
"1": 46
|
||||
},
|
||||
"flags": {},
|
||||
"order": 5,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 42
|
||||
},
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 53
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "drive_params",
|
||||
"type": "DRIVE_PARAMS",
|
||||
"links": [
|
||||
57
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "GetVideoDriveParams"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 38,
|
||||
"type": "PreviewImage",
|
||||
"pos": {
|
||||
"0": 1483,
|
||||
"1": 508
|
||||
},
|
||||
"size": [
|
||||
210,
|
||||
246
|
||||
],
|
||||
"flags": {},
|
||||
"order": 9,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 58
|
||||
}
|
||||
],
|
||||
"outputs": [],
|
||||
"properties": {
|
||||
"Node name for S&R": "PreviewImage"
|
||||
"Node name for S&R": "GetDriveExpression"
|
||||
}
|
||||
},
|
||||
{
|
||||
"id": 37,
|
||||
"type": "HMPipelineImage",
|
||||
"pos": {
|
||||
"0": 1083,
|
||||
"1": 508
|
||||
},
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 262
|
||||
},
|
||||
"flags": {},
|
||||
"order": 8,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "hm_image_pipeline",
|
||||
"type": "HMIMAGEPIPELINE",
|
||||
"link": 54
|
||||
},
|
||||
{
|
||||
"name": "ref_image",
|
||||
"type": "IMAGE",
|
||||
"link": 55
|
||||
},
|
||||
{
|
||||
"name": "ref_rt",
|
||||
"type": "REFRT",
|
||||
"link": 56
|
||||
},
|
||||
{
|
||||
"name": "drive_params",
|
||||
"type": "DRIVE_PARAMS",
|
||||
"link": 57
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
58
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "HMPipelineImage"
|
||||
},
|
||||
"widgets_values": [
|
||||
0,
|
||||
"(best quality), highly detailed, ultra-detailed, headshot, person, well-placed five sense organs, looking at the viewer, centered composition, sharp focus, realistic skin texture",
|
||||
"",
|
||||
25,
|
||||
47116,
|
||||
"randomize",
|
||||
2
|
||||
]
|
||||
}
|
||||
],
|
||||
"links": [
|
||||
[
|
||||
31,
|
||||
56,
|
||||
8,
|
||||
0,
|
||||
25,
|
||||
39,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
32,
|
||||
57,
|
||||
2,
|
||||
0,
|
||||
25,
|
||||
39,
|
||||
1,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
34,
|
||||
25,
|
||||
0,
|
||||
26,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
42,
|
||||
62,
|
||||
2,
|
||||
0,
|
||||
31,
|
||||
43,
|
||||
0,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
50,
|
||||
25,
|
||||
64,
|
||||
43,
|
||||
0,
|
||||
11,
|
||||
44,
|
||||
2,
|
||||
"FACELANDMARKS222"
|
||||
],
|
||||
[
|
||||
65,
|
||||
2,
|
||||
0,
|
||||
44,
|
||||
0,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
115,
|
||||
57,
|
||||
0,
|
||||
43,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
51,
|
||||
116,
|
||||
57,
|
||||
0,
|
||||
44,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
118,
|
||||
39,
|
||||
0,
|
||||
58,
|
||||
2,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
119,
|
||||
2,
|
||||
0,
|
||||
11,
|
||||
58,
|
||||
1,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
53,
|
||||
36,
|
||||
120,
|
||||
44,
|
||||
0,
|
||||
58,
|
||||
3,
|
||||
"DRIVE_POSE"
|
||||
],
|
||||
[
|
||||
122,
|
||||
58,
|
||||
0,
|
||||
59,
|
||||
0,
|
||||
31,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
54,
|
||||
35,
|
||||
123,
|
||||
60,
|
||||
0,
|
||||
37,
|
||||
58,
|
||||
0,
|
||||
"HMIMAGEPIPELINE"
|
||||
],
|
||||
[
|
||||
55,
|
||||
25,
|
||||
124,
|
||||
61,
|
||||
0,
|
||||
37,
|
||||
58,
|
||||
4,
|
||||
"DRIVE_EXPRESSION"
|
||||
],
|
||||
[
|
||||
125,
|
||||
57,
|
||||
0,
|
||||
61,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
56,
|
||||
11,
|
||||
126,
|
||||
43,
|
||||
0,
|
||||
37,
|
||||
61,
|
||||
2,
|
||||
"REFRT"
|
||||
"FACELANDMARKS222"
|
||||
],
|
||||
[
|
||||
57,
|
||||
31,
|
||||
127,
|
||||
2,
|
||||
0,
|
||||
37,
|
||||
3,
|
||||
"DRIVE_PARAMS"
|
||||
],
|
||||
[
|
||||
58,
|
||||
37,
|
||||
61,
|
||||
0,
|
||||
38,
|
||||
0,
|
||||
"IMAGE"
|
||||
"FACE_TOOLKITS"
|
||||
]
|
||||
],
|
||||
"groups": [],
|
||||
"config": {},
|
||||
"extra": {
|
||||
"ds": {
|
||||
"scale": 0.8264462809917354,
|
||||
"scale": 0.7513148009015777,
|
||||
"offset": [
|
||||
484.16679729452585,
|
||||
79.12268905130395
|
||||
328.1068082440709,
|
||||
3.5829604274896685
|
||||
]
|
||||
}
|
||||
},
|
||||
|
||||

Binary file not shown.
|
Before Width: | Height: | Size: 271 KiB |

Binary file not shown.
|
After Width: | Height: | Size: 761 KiB |
+374
-299
@@ -1,87 +1,63 @@
|
||||
{
|
||||
"last_node_id": 34,
|
||||
"last_link_id": 52,
|
||||
"last_node_id": 56,
|
||||
"last_link_id": 114,
|
||||
"nodes": [
|
||||
{
|
||||
"id": 25,
|
||||
"type": "CropReferenceImage",
|
||||
"id": 44,
|
||||
"type": "GetDrivePose",
|
||||
"pos": {
|
||||
"0": 447,
|
||||
"1": 498
|
||||
"0": 852,
|
||||
"1": 661
|
||||
},
|
||||
"size": {
|
||||
"0": 252,
|
||||
"1": 46
|
||||
},
|
||||
"flags": {},
|
||||
"order": 4,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "image",
|
||||
"type": "IMAGE",
|
||||
"link": 31
|
||||
},
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 32
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
34,
|
||||
46,
|
||||
50
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "CropReferenceImage"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 26,
|
||||
"type": "PreviewImage",
|
||||
"pos": {
|
||||
"0": 795,
|
||||
"1": 121
|
||||
},
|
||||
"size": {
|
||||
"0": 210,
|
||||
"1": 246
|
||||
"0": 304.79998779296875,
|
||||
"1": 66
|
||||
},
|
||||
"flags": {},
|
||||
"order": 6,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 65
|
||||
},
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 34
|
||||
"link": 83
|
||||
},
|
||||
{
|
||||
"name": "landmarks",
|
||||
"type": "FACELANDMARKS222",
|
||||
"link": 64
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "drive_pose",
|
||||
"type": "DRIVE_POSE",
|
||||
"links": [
|
||||
100
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"outputs": [],
|
||||
"properties": {
|
||||
"Node name for S&R": "PreviewImage"
|
||||
"Node name for S&R": "GetDrivePose"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 32,
|
||||
"id": 53,
|
||||
"type": "HMPipelineVideo",
|
||||
"pos": {
|
||||
"0": 1106,
|
||||
"1": 463
|
||||
"0": 1258,
|
||||
"1": 562
|
||||
},
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 262
|
||||
"1": 326
|
||||
},
|
||||
"flags": {},
|
||||
"order": 8,
|
||||
@@ -90,22 +66,34 @@
|
||||
{
|
||||
"name": "hm_video_pipeline",
|
||||
"type": "HMVIDEOPIPELINE",
|
||||
"link": 52
|
||||
"link": 98
|
||||
},
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 97
|
||||
},
|
||||
{
|
||||
"name": "ref_image",
|
||||
"type": "IMAGE",
|
||||
"link": 46
|
||||
"link": 99
|
||||
},
|
||||
{
|
||||
"name": "ref_rt",
|
||||
"type": "REFRT",
|
||||
"link": 47
|
||||
"name": "drive_pose",
|
||||
"type": "DRIVE_POSE",
|
||||
"link": 100
|
||||
},
|
||||
{
|
||||
"name": "drive_params",
|
||||
"type": "DRIVE_PARAMS",
|
||||
"link": 48
|
||||
"name": "drive_exp",
|
||||
"type": "DRIVE_EXPRESSION",
|
||||
"link": null,
|
||||
"shape": 7
|
||||
},
|
||||
{
|
||||
"name": "drive_exp2",
|
||||
"type": "DRIVE_EXPRESSION2",
|
||||
"link": 111,
|
||||
"shape": 7
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
@@ -113,7 +101,7 @@
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
44
|
||||
96
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
@@ -123,65 +111,104 @@
|
||||
},
|
||||
"widgets_values": [
|
||||
0,
|
||||
4,
|
||||
"(best quality), highly detailed, ultra-detailed, headshot, person, well-placed five sense organs, looking at the viewer, centered composition, sharp focus, realistic skin texture",
|
||||
"",
|
||||
25,
|
||||
13113,
|
||||
"randomize",
|
||||
98354,
|
||||
"fixed",
|
||||
2
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 31,
|
||||
"type": "GetVideoDriveParams",
|
||||
"id": 8,
|
||||
"type": "LoadImage",
|
||||
"pos": {
|
||||
"0": 447,
|
||||
"1": 745
|
||||
"0": 24,
|
||||
"1": 133
|
||||
},
|
||||
"size": {
|
||||
"0": 330,
|
||||
"0": 426.5283508300781,
|
||||
"1": 476.4518127441406
|
||||
},
|
||||
"flags": {},
|
||||
"order": 0,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
56
|
||||
],
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "MASK",
|
||||
"type": "MASK",
|
||||
"links": null
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadImage"
|
||||
},
|
||||
"widgets_values": [
|
||||
"majicmix2.jpg",
|
||||
"image"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 39,
|
||||
"type": "CropPortrait",
|
||||
"pos": {
|
||||
"0": 516,
|
||||
"1": 537
|
||||
},
|
||||
"size": {
|
||||
"0": 241.79998779296875,
|
||||
"1": 46
|
||||
},
|
||||
"flags": {},
|
||||
"order": 5,
|
||||
"order": 4,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 42
|
||||
"name": "image",
|
||||
"type": "IMAGE",
|
||||
"link": 56
|
||||
},
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 43
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 57
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "drive_params",
|
||||
"type": "DRIVE_PARAMS",
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
48
|
||||
99
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "GetVideoDriveParams"
|
||||
"Node name for S&R": "CropPortrait"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 21,
|
||||
"id": 52,
|
||||
"type": "VHS_VideoCombine",
|
||||
"pos": {
|
||||
"0": 1502,
|
||||
"1": 613
|
||||
"0": 1658,
|
||||
"1": 894
|
||||
},
|
||||
"size": [
|
||||
214.7587890625,
|
||||
518.7587890625
|
||||
289.33306884765625,
|
||||
593.3330688476562
|
||||
],
|
||||
"flags": {},
|
||||
"order": 9,
|
||||
@@ -190,12 +217,12 @@
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 44
|
||||
"link": 96
|
||||
},
|
||||
{
|
||||
"name": "audio",
|
||||
"type": "AUDIO",
|
||||
"link": 25,
|
||||
"link": 92,
|
||||
"shape": 7
|
||||
},
|
||||
{
|
||||
@@ -215,7 +242,7 @@
|
||||
{
|
||||
"name": "Filenames",
|
||||
"type": "VHS_FILENAMES",
|
||||
"links": []
|
||||
"links": null
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
@@ -224,10 +251,10 @@
|
||||
"widgets_values": {
|
||||
"frame_rate": 15,
|
||||
"loop_count": 0,
|
||||
"filename_prefix": "HelloMeme",
|
||||
"filename_prefix": "AnimateDiff",
|
||||
"format": "video/h264-mp4",
|
||||
"pix_fmt": "yuv420p",
|
||||
"crf": 19,
|
||||
"crf": 18,
|
||||
"save_metadata": true,
|
||||
"pingpong": false,
|
||||
"save_output": true,
|
||||
@@ -235,7 +262,7 @@
|
||||
"hidden": false,
|
||||
"paused": false,
|
||||
"params": {
|
||||
"filename": "HelloMeme_00073-audio.mp4",
|
||||
"filename": "AnimateDiff_00026-audio.mp4",
|
||||
"subfolder": "",
|
||||
"type": "output",
|
||||
"format": "video/h264-mp4",
|
||||
@@ -246,81 +273,90 @@
|
||||
}
|
||||
},
|
||||
{
|
||||
"id": 8,
|
||||
"type": "LoadImage",
|
||||
"id": 56,
|
||||
"type": "GetDriveExpression2",
|
||||
"pos": {
|
||||
"0": 61,
|
||||
"1": 290
|
||||
"0": 852,
|
||||
"1": 801
|
||||
},
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 314
|
||||
},
|
||||
"flags": {},
|
||||
"order": 0,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
31
|
||||
],
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "MASK",
|
||||
"type": "MASK",
|
||||
"links": null
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadImage"
|
||||
},
|
||||
"widgets_values": [
|
||||
"majicmix2.jpg",
|
||||
"image"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 11,
|
||||
"type": "GetReferenceImageRT",
|
||||
"pos": {
|
||||
"0": 749,
|
||||
"1": 546
|
||||
},
|
||||
"size": {
|
||||
"0": 241.79998779296875,
|
||||
"1": 46
|
||||
"0": 304.79998779296875,
|
||||
"1": 66
|
||||
},
|
||||
"flags": {},
|
||||
"order": 7,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "image",
|
||||
"type": "IMAGE",
|
||||
"link": 50
|
||||
},
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 51
|
||||
"link": 114
|
||||
},
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 112
|
||||
},
|
||||
{
|
||||
"name": "landmarks",
|
||||
"type": "FACELANDMARKS222",
|
||||
"link": 113
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "ref_rt",
|
||||
"type": "REFRT",
|
||||
"name": "drive_exp2",
|
||||
"type": "DRIVE_EXPRESSION2",
|
||||
"links": [
|
||||
47
|
||||
111
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "GetReferenceImageRT"
|
||||
"Node name for S&R": "GetDriveExpression2"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 43,
|
||||
"type": "GetFaceLandmarks",
|
||||
"pos": {
|
||||
"0": 465,
|
||||
"1": 771
|
||||
},
|
||||
"size": {
|
||||
"0": 292.20001220703125,
|
||||
"1": 46
|
||||
},
|
||||
"flags": {},
|
||||
"order": 5,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 62
|
||||
},
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 82
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "landmarks",
|
||||
"type": "FACELANDMARKS222",
|
||||
"links": [
|
||||
64,
|
||||
113
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "GetFaceLandmarks"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
@@ -328,8 +364,8 @@
|
||||
"id": 2,
|
||||
"type": "HMFaceToolkitsLoader",
|
||||
"pos": {
|
||||
"0": 61,
|
||||
"1": 697
|
||||
"0": 43,
|
||||
"1": 699
|
||||
},
|
||||
"size": {
|
||||
"0": 315,
|
||||
@@ -344,9 +380,11 @@
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"links": [
|
||||
32,
|
||||
42,
|
||||
51
|
||||
57,
|
||||
62,
|
||||
65,
|
||||
97,
|
||||
114
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
@@ -359,19 +397,54 @@
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 20,
|
||||
"type": "VHS_LoadVideoFFmpeg",
|
||||
"id": 49,
|
||||
"type": "HMVideoPipelineLoader",
|
||||
"pos": {
|
||||
"0": 66,
|
||||
"1": 835
|
||||
"0": 849,
|
||||
"1": 375
|
||||
},
|
||||
"size": {
|
||||
"0": 352.79998779296875,
|
||||
"1": 130
|
||||
},
|
||||
"size": [
|
||||
303.46875,
|
||||
535.46875
|
||||
],
|
||||
"flags": {},
|
||||
"order": 2,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "hm_video_pipeline",
|
||||
"type": "HMVIDEOPIPELINE",
|
||||
"links": [
|
||||
98
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "HMVideoPipelineLoader"
|
||||
},
|
||||
"widgets_values": [
|
||||
"SD1.5",
|
||||
"None",
|
||||
12,
|
||||
0
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 48,
|
||||
"type": "VHS_LoadVideo",
|
||||
"pos": {
|
||||
"0": 75,
|
||||
"1": 900
|
||||
},
|
||||
"size": [
|
||||
247.455078125,
|
||||
503.455078125
|
||||
],
|
||||
"flags": {},
|
||||
"order": 3,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "meta_batch",
|
||||
@@ -391,20 +464,22 @@
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
43
|
||||
82,
|
||||
83,
|
||||
112
|
||||
],
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "mask",
|
||||
"type": "MASK",
|
||||
"name": "frame_count",
|
||||
"type": "INT",
|
||||
"links": null
|
||||
},
|
||||
{
|
||||
"name": "audio",
|
||||
"type": "AUDIO",
|
||||
"links": [
|
||||
25
|
||||
92
|
||||
],
|
||||
"slot_index": 2
|
||||
},
|
||||
@@ -415,7 +490,7 @@
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "VHS_LoadVideoFFmpeg"
|
||||
"Node name for S&R": "VHS_LoadVideo"
|
||||
},
|
||||
"widgets_values": {
|
||||
"video": "jgz.mp4",
|
||||
@@ -424,7 +499,8 @@
|
||||
"custom_width": 512,
|
||||
"custom_height": 512,
|
||||
"frame_load_cap": 0,
|
||||
"start_time": 0,
|
||||
"skip_first_frames": 0,
|
||||
"select_every_nth": 1,
|
||||
"choose video to upload": "image",
|
||||
"videopreview": {
|
||||
"hidden": false,
|
||||
@@ -432,7 +508,8 @@
|
||||
"params": {
|
||||
"force_rate": 15,
|
||||
"frame_load_cap": 0,
|
||||
"start_time": 0,
|
||||
"skip_first_frames": 0,
|
||||
"select_every_nth": 1,
|
||||
"filename": "jgz.mp4",
|
||||
"type": "input",
|
||||
"format": "video/mp4"
|
||||
@@ -440,156 +517,154 @@
|
||||
"muted": false
|
||||
}
|
||||
}
|
||||
},
|
||||
{
|
||||
"id": 34,
|
||||
"type": "HMVideoSimplePipelineLoader",
|
||||
"pos": {
|
||||
"0": 56,
|
||||
"1": 85
|
||||
},
|
||||
"size": {
|
||||
"0": 428.4000244140625,
|
||||
"1": 106
|
||||
},
|
||||
"flags": {},
|
||||
"order": 3,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "hm_video_pipeline",
|
||||
"type": "HMVIDEOPIPELINE",
|
||||
"links": [
|
||||
52
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "HMVideoSimplePipelineLoader"
|
||||
},
|
||||
"widgets_values": [
|
||||
"SD1.5",
|
||||
"None",
|
||||
0
|
||||
]
|
||||
}
|
||||
],
|
||||
"links": [
|
||||
[
|
||||
25,
|
||||
20,
|
||||
56,
|
||||
8,
|
||||
0,
|
||||
39,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
57,
|
||||
2,
|
||||
21,
|
||||
0,
|
||||
39,
|
||||
1,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
62,
|
||||
2,
|
||||
0,
|
||||
43,
|
||||
0,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
64,
|
||||
43,
|
||||
0,
|
||||
44,
|
||||
2,
|
||||
"FACELANDMARKS222"
|
||||
],
|
||||
[
|
||||
65,
|
||||
2,
|
||||
0,
|
||||
44,
|
||||
0,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
82,
|
||||
48,
|
||||
0,
|
||||
43,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
83,
|
||||
48,
|
||||
0,
|
||||
44,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
92,
|
||||
48,
|
||||
2,
|
||||
52,
|
||||
1,
|
||||
"AUDIO"
|
||||
],
|
||||
[
|
||||
31,
|
||||
8,
|
||||
96,
|
||||
53,
|
||||
0,
|
||||
25,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
32,
|
||||
2,
|
||||
0,
|
||||
25,
|
||||
1,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
34,
|
||||
25,
|
||||
0,
|
||||
26,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
42,
|
||||
2,
|
||||
0,
|
||||
31,
|
||||
0,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
43,
|
||||
20,
|
||||
0,
|
||||
31,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
44,
|
||||
32,
|
||||
0,
|
||||
21,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
46,
|
||||
25,
|
||||
0,
|
||||
32,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
47,
|
||||
11,
|
||||
0,
|
||||
32,
|
||||
2,
|
||||
"REFRT"
|
||||
],
|
||||
[
|
||||
48,
|
||||
31,
|
||||
0,
|
||||
32,
|
||||
3,
|
||||
"DRIVE_PARAMS"
|
||||
],
|
||||
[
|
||||
50,
|
||||
25,
|
||||
0,
|
||||
11,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
51,
|
||||
2,
|
||||
0,
|
||||
11,
|
||||
1,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
52,
|
||||
34,
|
||||
0,
|
||||
32,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
97,
|
||||
2,
|
||||
0,
|
||||
53,
|
||||
1,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
98,
|
||||
49,
|
||||
0,
|
||||
53,
|
||||
0,
|
||||
"HMVIDEOPIPELINE"
|
||||
],
|
||||
[
|
||||
99,
|
||||
39,
|
||||
0,
|
||||
53,
|
||||
2,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
100,
|
||||
44,
|
||||
0,
|
||||
53,
|
||||
3,
|
||||
"DRIVE_POSE"
|
||||
],
|
||||
[
|
||||
111,
|
||||
56,
|
||||
0,
|
||||
53,
|
||||
5,
|
||||
"DRIVE_EXPRESSION2"
|
||||
],
|
||||
[
|
||||
112,
|
||||
48,
|
||||
0,
|
||||
56,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
113,
|
||||
43,
|
||||
0,
|
||||
56,
|
||||
2,
|
||||
"FACELANDMARKS222"
|
||||
],
|
||||
[
|
||||
114,
|
||||
2,
|
||||
0,
|
||||
56,
|
||||
0,
|
||||
"FACE_TOOLKITS"
|
||||
]
|
||||
],
|
||||
"groups": [],
|
||||
"config": {},
|
||||
"extra": {
|
||||
"ds": {
|
||||
"scale": 0.8264462809917354,
|
||||
"scale": 0.7513148009015777,
|
||||
"offset": [
|
||||
483.3601798628852,
|
||||
79.12268905130395
|
||||
760.8618864750447,
|
||||
109.23033266581292
|
||||
]
|
||||
}
|
||||
},
|
||||
@@ -1,87 +1,63 @@
|
||||
{
|
||||
"last_node_id": 33,
|
||||
"last_link_id": 51,
|
||||
"last_node_id": 55,
|
||||
"last_link_id": 110,
|
||||
"nodes": [
|
||||
{
|
||||
"id": 25,
|
||||
"type": "CropReferenceImage",
|
||||
"id": 44,
|
||||
"type": "GetDrivePose",
|
||||
"pos": {
|
||||
"0": 447,
|
||||
"1": 498
|
||||
"0": 852,
|
||||
"1": 661
|
||||
},
|
||||
"size": {
|
||||
"0": 252,
|
||||
"1": 46
|
||||
},
|
||||
"flags": {},
|
||||
"order": 4,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "image",
|
||||
"type": "IMAGE",
|
||||
"link": 31
|
||||
},
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 32
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
34,
|
||||
46,
|
||||
50
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "CropReferenceImage"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 26,
|
||||
"type": "PreviewImage",
|
||||
"pos": {
|
||||
"0": 795,
|
||||
"1": 121
|
||||
},
|
||||
"size": {
|
||||
"0": 210,
|
||||
"1": 246
|
||||
"0": 304.79998779296875,
|
||||
"1": 66
|
||||
},
|
||||
"flags": {},
|
||||
"order": 6,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 65
|
||||
},
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 34
|
||||
"link": 83
|
||||
},
|
||||
{
|
||||
"name": "landmarks",
|
||||
"type": "FACELANDMARKS222",
|
||||
"link": 64
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "drive_pose",
|
||||
"type": "DRIVE_POSE",
|
||||
"links": [
|
||||
100
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"outputs": [],
|
||||
"properties": {
|
||||
"Node name for S&R": "PreviewImage"
|
||||
"Node name for S&R": "GetDrivePose"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 32,
|
||||
"id": 53,
|
||||
"type": "HMPipelineVideo",
|
||||
"pos": {
|
||||
"0": 1106,
|
||||
"1": 463
|
||||
"0": 1258,
|
||||
"1": 562
|
||||
},
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 262
|
||||
"1": 326
|
||||
},
|
||||
"flags": {},
|
||||
"order": 8,
|
||||
@@ -90,22 +66,34 @@
|
||||
{
|
||||
"name": "hm_video_pipeline",
|
||||
"type": "HMVIDEOPIPELINE",
|
||||
"link": 49
|
||||
"link": 98
|
||||
},
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 97
|
||||
},
|
||||
{
|
||||
"name": "ref_image",
|
||||
"type": "IMAGE",
|
||||
"link": 46
|
||||
"link": 99
|
||||
},
|
||||
{
|
||||
"name": "ref_rt",
|
||||
"type": "REFRT",
|
||||
"link": 47
|
||||
"name": "drive_pose",
|
||||
"type": "DRIVE_POSE",
|
||||
"link": 100
|
||||
},
|
||||
{
|
||||
"name": "drive_params",
|
||||
"type": "DRIVE_PARAMS",
|
||||
"link": 48
|
||||
"name": "drive_exp",
|
||||
"type": "DRIVE_EXPRESSION",
|
||||
"link": 110,
|
||||
"shape": 7
|
||||
},
|
||||
{
|
||||
"name": "drive_exp2",
|
||||
"type": "DRIVE_EXPRESSION2",
|
||||
"link": null,
|
||||
"shape": 7
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
@@ -113,7 +101,7 @@
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
44
|
||||
96
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
@@ -123,23 +111,139 @@
|
||||
},
|
||||
"widgets_values": [
|
||||
0,
|
||||
4,
|
||||
"(best quality), highly detailed, ultra-detailed, headshot, person, well-placed five sense organs, looking at the viewer, centered composition, sharp focus, realistic skin texture",
|
||||
"",
|
||||
25,
|
||||
32295,
|
||||
"randomize",
|
||||
98354,
|
||||
"fixed",
|
||||
2
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 31,
|
||||
"type": "GetVideoDriveParams",
|
||||
"id": 2,
|
||||
"type": "HMFaceToolkitsLoader",
|
||||
"pos": {
|
||||
"0": 447,
|
||||
"1": 745
|
||||
"0": 43,
|
||||
"1": 699
|
||||
},
|
||||
"size": {
|
||||
"0": 330,
|
||||
"0": 315,
|
||||
"1": 58
|
||||
},
|
||||
"flags": {},
|
||||
"order": 0,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"links": [
|
||||
57,
|
||||
62,
|
||||
65,
|
||||
97,
|
||||
109
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "HMFaceToolkitsLoader"
|
||||
},
|
||||
"widgets_values": [
|
||||
0
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 8,
|
||||
"type": "LoadImage",
|
||||
"pos": {
|
||||
"0": 24,
|
||||
"1": 133
|
||||
},
|
||||
"size": {
|
||||
"0": 426.5283508300781,
|
||||
"1": 476.4518127441406
|
||||
},
|
||||
"flags": {},
|
||||
"order": 1,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
56
|
||||
],
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "MASK",
|
||||
"type": "MASK",
|
||||
"links": null
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadImage"
|
||||
},
|
||||
"widgets_values": [
|
||||
"majicmix2.jpg",
|
||||
"image"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 39,
|
||||
"type": "CropPortrait",
|
||||
"pos": {
|
||||
"0": 516,
|
||||
"1": 537
|
||||
},
|
||||
"size": {
|
||||
"0": 241.79998779296875,
|
||||
"1": 46
|
||||
},
|
||||
"flags": {},
|
||||
"order": 4,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "image",
|
||||
"type": "IMAGE",
|
||||
"link": 56
|
||||
},
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 57
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
99
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "CropPortrait"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 43,
|
||||
"type": "GetFaceLandmarks",
|
||||
"pos": {
|
||||
"0": 465,
|
||||
"1": 771
|
||||
},
|
||||
"size": {
|
||||
"0": 292.20001220703125,
|
||||
"1": 46
|
||||
},
|
||||
"flags": {},
|
||||
@@ -149,39 +253,127 @@
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 42
|
||||
"link": 62
|
||||
},
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 43
|
||||
"link": 82
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "drive_params",
|
||||
"type": "DRIVE_PARAMS",
|
||||
"name": "landmarks",
|
||||
"type": "FACELANDMARKS222",
|
||||
"links": [
|
||||
48
|
||||
64,
|
||||
107
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "GetVideoDriveParams"
|
||||
"Node name for S&R": "GetFaceLandmarks"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 21,
|
||||
"id": 48,
|
||||
"type": "VHS_LoadVideo",
|
||||
"pos": {
|
||||
"0": 75,
|
||||
"1": 900
|
||||
},
|
||||
"size": {
|
||||
"0": 247.455078125,
|
||||
"1": 262
|
||||
},
|
||||
"flags": {},
|
||||
"order": 2,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "meta_batch",
|
||||
"type": "VHS_BatchManager",
|
||||
"link": null,
|
||||
"shape": 7
|
||||
},
|
||||
{
|
||||
"name": "vae",
|
||||
"type": "VAE",
|
||||
"link": null,
|
||||
"shape": 7
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
82,
|
||||
83,
|
||||
108
|
||||
],
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "frame_count",
|
||||
"type": "INT",
|
||||
"links": null
|
||||
},
|
||||
{
|
||||
"name": "audio",
|
||||
"type": "AUDIO",
|
||||
"links": [
|
||||
92
|
||||
],
|
||||
"slot_index": 2
|
||||
},
|
||||
{
|
||||
"name": "video_info",
|
||||
"type": "VHS_VIDEOINFO",
|
||||
"links": null
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "VHS_LoadVideo"
|
||||
},
|
||||
"widgets_values": {
|
||||
"video": "jgz.mp4",
|
||||
"force_rate": 15,
|
||||
"force_size": "Disabled",
|
||||
"custom_width": 512,
|
||||
"custom_height": 512,
|
||||
"frame_load_cap": 0,
|
||||
"skip_first_frames": 0,
|
||||
"select_every_nth": 1,
|
||||
"choose video to upload": "image",
|
||||
"videopreview": {
|
||||
"hidden": false,
|
||||
"paused": false,
|
||||
"params": {
|
||||
"force_rate": 15,
|
||||
"frame_load_cap": 0,
|
||||
"skip_first_frames": 0,
|
||||
"select_every_nth": 1,
|
||||
"filename": "jgz.mp4",
|
||||
"type": "input",
|
||||
"format": "video/mp4"
|
||||
},
|
||||
"muted": false
|
||||
}
|
||||
}
|
||||
},
|
||||
{
|
||||
"id": 52,
|
||||
"type": "VHS_VideoCombine",
|
||||
"pos": {
|
||||
"0": 1502,
|
||||
"1": 613
|
||||
"0": 1658,
|
||||
"1": 894
|
||||
},
|
||||
"size": [
|
||||
214.7587890625,
|
||||
518.7587890625
|
||||
289.33306884765625,
|
||||
593.3330688476562
|
||||
],
|
||||
"flags": {},
|
||||
"order": 9,
|
||||
@@ -190,12 +382,12 @@
|
||||
{
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 44
|
||||
"link": 96
|
||||
},
|
||||
{
|
||||
"name": "audio",
|
||||
"type": "AUDIO",
|
||||
"link": 25,
|
||||
"link": 92,
|
||||
"shape": 7
|
||||
},
|
||||
{
|
||||
@@ -215,7 +407,7 @@
|
||||
{
|
||||
"name": "Filenames",
|
||||
"type": "VHS_FILENAMES",
|
||||
"links": []
|
||||
"links": null
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
@@ -224,10 +416,10 @@
|
||||
"widgets_values": {
|
||||
"frame_rate": 15,
|
||||
"loop_count": 0,
|
||||
"filename_prefix": "HelloMeme",
|
||||
"filename_prefix": "AnimateDiff",
|
||||
"format": "video/h264-mp4",
|
||||
"pix_fmt": "yuv420p",
|
||||
"crf": 19,
|
||||
"crf": 18,
|
||||
"save_metadata": true,
|
||||
"pingpong": false,
|
||||
"save_output": true,
|
||||
@@ -235,10 +427,10 @@
|
||||
"hidden": false,
|
||||
"paused": false,
|
||||
"params": {
|
||||
"filename": "HelloMeme_00067-audio.mp4",
|
||||
"filename": "AnimateDiff_00023.gif",
|
||||
"subfolder": "",
|
||||
"type": "output",
|
||||
"format": "video/h264-mp4",
|
||||
"format": "image/gif",
|
||||
"frame_rate": 15
|
||||
},
|
||||
"muted": false
|
||||
@@ -246,56 +438,64 @@
|
||||
}
|
||||
},
|
||||
{
|
||||
"id": 8,
|
||||
"type": "LoadImage",
|
||||
"id": 55,
|
||||
"type": "GetDriveExpression",
|
||||
"pos": {
|
||||
"0": 61,
|
||||
"1": 290
|
||||
"0": 857,
|
||||
"1": 815
|
||||
},
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 314
|
||||
"0": 292.20001220703125,
|
||||
"1": 66
|
||||
},
|
||||
"flags": {},
|
||||
"order": 0,
|
||||
"order": 7,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
"inputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
31
|
||||
],
|
||||
"slot_index": 0
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 109
|
||||
},
|
||||
{
|
||||
"name": "MASK",
|
||||
"type": "MASK",
|
||||
"links": null
|
||||
"name": "images",
|
||||
"type": "IMAGE",
|
||||
"link": 108
|
||||
},
|
||||
{
|
||||
"name": "landmarks",
|
||||
"type": "FACELANDMARKS222",
|
||||
"link": 107
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "drive_exp",
|
||||
"type": "DRIVE_EXPRESSION",
|
||||
"links": [
|
||||
110
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadImage"
|
||||
"Node name for S&R": "GetDriveExpression"
|
||||
},
|
||||
"widgets_values": [
|
||||
"majicmix2.jpg",
|
||||
"image"
|
||||
]
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 33,
|
||||
"id": 49,
|
||||
"type": "HMVideoPipelineLoader",
|
||||
"pos": {
|
||||
"0": 66,
|
||||
"1": 85
|
||||
"0": 849,
|
||||
"1": 375
|
||||
},
|
||||
"size": {
|
||||
"0": 352.79998779296875,
|
||||
"1": 130
|
||||
},
|
||||
"flags": {},
|
||||
"order": 1,
|
||||
"order": 3,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
@@ -303,7 +503,7 @@
|
||||
"name": "hm_video_pipeline",
|
||||
"type": "HMVIDEOPIPELINE",
|
||||
"links": [
|
||||
49
|
||||
98
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
@@ -317,280 +517,154 @@
|
||||
12,
|
||||
0
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 11,
|
||||
"type": "GetReferenceImageRT",
|
||||
"pos": {
|
||||
"0": 749,
|
||||
"1": 546
|
||||
},
|
||||
"size": {
|
||||
"0": 241.79998779296875,
|
||||
"1": 46
|
||||
},
|
||||
"flags": {},
|
||||
"order": 7,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "image",
|
||||
"type": "IMAGE",
|
||||
"link": 50
|
||||
},
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"link": 51
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "ref_rt",
|
||||
"type": "REFRT",
|
||||
"links": [
|
||||
47
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "GetReferenceImageRT"
|
||||
},
|
||||
"widgets_values": []
|
||||
},
|
||||
{
|
||||
"id": 2,
|
||||
"type": "HMFaceToolkitsLoader",
|
||||
"pos": {
|
||||
"0": 61,
|
||||
"1": 697
|
||||
},
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 58
|
||||
},
|
||||
"flags": {},
|
||||
"order": 2,
|
||||
"mode": 0,
|
||||
"inputs": [],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "face_toolkits",
|
||||
"type": "FACE_TOOLKITS",
|
||||
"links": [
|
||||
32,
|
||||
42,
|
||||
51
|
||||
],
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "HMFaceToolkitsLoader"
|
||||
},
|
||||
"widgets_values": [
|
||||
0
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 20,
|
||||
"type": "VHS_LoadVideoFFmpeg",
|
||||
"pos": {
|
||||
"0": 66,
|
||||
"1": 835
|
||||
},
|
||||
"size": [
|
||||
303.46875,
|
||||
535.46875
|
||||
],
|
||||
"flags": {},
|
||||
"order": 3,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "meta_batch",
|
||||
"type": "VHS_BatchManager",
|
||||
"link": null,
|
||||
"shape": 7
|
||||
},
|
||||
{
|
||||
"name": "vae",
|
||||
"type": "VAE",
|
||||
"link": null,
|
||||
"shape": 7
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
43
|
||||
],
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "mask",
|
||||
"type": "MASK",
|
||||
"links": null
|
||||
},
|
||||
{
|
||||
"name": "audio",
|
||||
"type": "AUDIO",
|
||||
"links": [
|
||||
25
|
||||
],
|
||||
"slot_index": 2
|
||||
},
|
||||
{
|
||||
"name": "video_info",
|
||||
"type": "VHS_VIDEOINFO",
|
||||
"links": null
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "VHS_LoadVideoFFmpeg"
|
||||
},
|
||||
"widgets_values": {
|
||||
"video": "jgz.mp4",
|
||||
"force_rate": 15,
|
||||
"force_size": "Disabled",
|
||||
"custom_width": 512,
|
||||
"custom_height": 512,
|
||||
"frame_load_cap": 0,
|
||||
"start_time": 0,
|
||||
"choose video to upload": "image",
|
||||
"videopreview": {
|
||||
"hidden": false,
|
||||
"paused": false,
|
||||
"params": {
|
||||
"force_rate": 15,
|
||||
"frame_load_cap": 0,
|
||||
"start_time": 0,
|
||||
"filename": "jgz.mp4",
|
||||
"type": "input",
|
||||
"format": "video/mp4"
|
||||
},
|
||||
"muted": false
|
||||
}
|
||||
}
|
||||
}
|
||||
],
|
||||
"links": [
|
||||
[
|
||||
25,
|
||||
20,
|
||||
56,
|
||||
8,
|
||||
0,
|
||||
39,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
57,
|
||||
2,
|
||||
21,
|
||||
0,
|
||||
39,
|
||||
1,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
62,
|
||||
2,
|
||||
0,
|
||||
43,
|
||||
0,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
64,
|
||||
43,
|
||||
0,
|
||||
44,
|
||||
2,
|
||||
"FACELANDMARKS222"
|
||||
],
|
||||
[
|
||||
65,
|
||||
2,
|
||||
0,
|
||||
44,
|
||||
0,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
82,
|
||||
48,
|
||||
0,
|
||||
43,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
83,
|
||||
48,
|
||||
0,
|
||||
44,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
92,
|
||||
48,
|
||||
2,
|
||||
52,
|
||||
1,
|
||||
"AUDIO"
|
||||
],
|
||||
[
|
||||
31,
|
||||
8,
|
||||
96,
|
||||
53,
|
||||
0,
|
||||
25,
|
||||
52,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
32,
|
||||
97,
|
||||
2,
|
||||
0,
|
||||
25,
|
||||
53,
|
||||
1,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
34,
|
||||
25,
|
||||
0,
|
||||
26,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
42,
|
||||
2,
|
||||
0,
|
||||
31,
|
||||
0,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
43,
|
||||
20,
|
||||
0,
|
||||
31,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
44,
|
||||
32,
|
||||
0,
|
||||
21,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
46,
|
||||
25,
|
||||
0,
|
||||
32,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
47,
|
||||
11,
|
||||
0,
|
||||
32,
|
||||
2,
|
||||
"REFRT"
|
||||
],
|
||||
[
|
||||
48,
|
||||
31,
|
||||
0,
|
||||
32,
|
||||
3,
|
||||
"DRIVE_PARAMS"
|
||||
],
|
||||
[
|
||||
98,
|
||||
49,
|
||||
33,
|
||||
0,
|
||||
32,
|
||||
53,
|
||||
0,
|
||||
"HMVIDEOPIPELINE"
|
||||
],
|
||||
[
|
||||
50,
|
||||
25,
|
||||
0,
|
||||
11,
|
||||
99,
|
||||
39,
|
||||
0,
|
||||
53,
|
||||
2,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
51,
|
||||
100,
|
||||
44,
|
||||
0,
|
||||
53,
|
||||
3,
|
||||
"DRIVE_POSE"
|
||||
],
|
||||
[
|
||||
107,
|
||||
43,
|
||||
0,
|
||||
55,
|
||||
2,
|
||||
"FACELANDMARKS222"
|
||||
],
|
||||
[
|
||||
108,
|
||||
48,
|
||||
0,
|
||||
55,
|
||||
1,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
109,
|
||||
2,
|
||||
0,
|
||||
11,
|
||||
1,
|
||||
55,
|
||||
0,
|
||||
"FACE_TOOLKITS"
|
||||
],
|
||||
[
|
||||
110,
|
||||
55,
|
||||
0,
|
||||
53,
|
||||
4,
|
||||
"DRIVE_EXPRESSION"
|
||||
]
|
||||
],
|
||||
"groups": [],
|
||||
"config": {},
|
||||
"extra": {
|
||||
"ds": {
|
||||
"scale": 0.8264462809917354,
|
||||
"scale": 0.7513148009015777,
|
||||
"offset": [
|
||||
482.55341472616647,
|
||||
79.12268905130395
|
||||
760.8618864750447,
|
||||
107.45573369730707
|
||||
]
|
||||
}
|
||||
},
|
||||
|
||||
Reference in New Issue
Block a user