Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 huangkunzhe.hkz |
9b86fff645 | ||
|
Bubbliiiing
|
a6b026526f | ||
|
Bubbliiiing
|
0f0e2bd5ab | ||
|
Bubbliiiing
|
0af07603da | ||
|
Bubbliiiing
|
7671af8b16 | ||
|
Bubbliiiing
|
95737c8f1d | ||
|
Bubbliiiing
|
ac114cc142 | ||
|
Bubbliiiing
|
b534ebfef1 | ||
|
Bubbliiiing
|
e9d5b09c92 | ||
|
Bubbliiiing
|
a4783c4364 | ||
|
Bubbliiiing
|
5eb0c6862f | ||
|
Bubbliiiing
|
a0ba11bc0e | ||
|
Bubbliiiing
|
73dc7a3134 | ||
|
hobbyandBubbliiiing
|
346f835af7 | ||
|
Bubbliiiing
|
d9caf3f9c0 | ||
|
Bubbliiiing
|
2faa27e6b0 | ||
|
Bubbliiiing
|
246a0e3a22 | ||
|
Silver
|
244f110531 | ||
|
Bubbliiiing
|
df665a82c8 | ||
|
Bubbliiiing
|
ca4cc1522f | ||
|
Bubbliiiing
|
d0fcc4d459 | ||
|
Bubbliiiing
|
d62ae3d2ca | ||
|
Bubbliiiing
|
4935a70391 | ||
|
Bubbliiiing
|
790a1555f0 | ||
|
Bubbliiiing
|
ce53fb9f3c | ||
|
Bubbliiiing
|
6a95acc2b7 | ||
|
Bubbliiiing
|
200e1f3224 | ||
|
Bubbliiiing
|
5794017c00 | ||
|
Bubbliiiing
|
599e797e9e | ||
|
Bubbliiiing
|
037a2e8360 | ||
|
Bubbliiiing
|
ccc3b1055e | ||
|
Bubbliiiing
|
7cabe7642d | ||
|
Bubbliiiing
|
7fd9594919 | ||
|
Bubbliiiing
|
df77df019e | ||
|
Bubbliiiing
|
ce7ff41bfb | ||
|
Bubbliiiing
|
9dbe1ea261 | ||
|
Bubbliiiing
|
fe06f8958a | ||
|
Bubbliiiing
|
900b181ac6 | ||
|
Bubbliiiing
|
8c34acc600 | ||
|
Bubbliiiing
|
6844755d78 | ||
|
Bubbliiiing
|
6183d41df8 | ||
|
Bubbliiiing
|
7851e14319 | ||
|
Bubbliiiing
|
0419d8936d | ||
|
Bubbliiiing
|
bd0f0ca1ed | ||
|
Bubbliiiing
|
e1c1a9562f | ||
|
王泽鹏
|
add6b679a4 | ||
|
Bubbliiiing
|
3e8d6867d3 | ||
|
Bubbliiiing
|
e98eb1385c | ||
|
Bubbliiiing
|
a40638f853 | ||
|
Bubbliiiing
|
abeac38889 | ||
|
Bubbliiiing
|
1d6d9c3e15 | ||
|
Bubbliiiing
|
37bd735647 | ||
|
hkz
|
0398977604 | ||
|
Bubbliiiing
|
74426601fa | ||
|
Bubbliiiing
|
427fba66a9 | ||
|
Bubbliiiing
|
b9d3b2aacd | ||
|
Bubbliiiing
|
2e165b7216 | ||
|
Leojc
|
8f8c85693d | ||
|
Leojc
|
15d6fd8137 | ||
|
Bubbliiiing
|
6a13aa5116 | ||
|
Bubbliiiing
|
7157cdd48a | ||
|
Bubbliiiing
|
24a5eed03b | ||
|
Bubbliiiing
|
eb915f0da3 | ||
|
Bubbliiiing
|
0bf937ea59 | ||
|
Bubbliiiing
|
5631a8cac4 | ||
|
Bubbliiiing
|
1a494b9188 | ||
|
Bubbliiiing
|
976121891e | ||
|
Bubbliiiing
|
e7d3b597fb | ||
|
flyingshan
|
ee8c09416b | ||
|
Bubbliiiing
|
4dc94d2b95 | ||
|
NoobNoob
|
34ef44eb52 | ||
|
Bubbliiiing
|
9c05f3a741 | ||
|
Bubbliiiing
|
2d3a5cc7d6 | ||
|
Bubbliiiing
|
a17b35acfb | ||
|
Tianhao-Qi
|
4f14db1269 | ||
|
Bubbliiiing
|
9436ff2f6e | ||
|
Bubbliiiing
|
9702fc9db6 | ||
|
Bubbliiiing
|
21ec5bf326 | ||
|
Bubbliiiing
|
dcd1b32ee6 | ||
|
bubbliiiing
|
89c8a2a138 | ||
|
Bubbliiiing
|
541f789188 | ||
|
huangkunzhe.hkz
|
9c16b3a73f | ||
|
liubo0902and宣源
|
c2d0c7ae21 | ||
|
Bubbliiiing
|
097208e817 | ||
|
Bubbliiiing
|
86028a9ce6 | ||
|
Bubbliiiing
|
ba1da31fb5 | ||
|
Bubbliiiing
|
ce452acc0c | ||
|
bubbliiiing
|
95e024c681 | ||
|
bubbliiiing
|
a4476549e4 | ||
|
bubbliiiing
|
72c2792139 | ||
|
bubbliiiing
|
e4c74a12f2 | ||
|
huangkunzhe.hkz
|
fab50bd721 | ||
|
Bubbliiiing
|
f176ca9b78 | ||
|
huangkunzhe.hkz
|
41e0a6a623 | ||
|
Bubbliiiing
|
ed5e3e5f69 | ||
|
bubbliiiing
|
a6a8383c45 | ||
|
Bubbliiiing
|
1061378b66 | ||
|
Bubbliiiing
|
6b6413a95c | ||
|
Bubbliiiing
|
a1e6ea6335 | ||
|
wzgrx
|
87125a4af0 | ||
|
Bubbliiiing
|
ed4f10beef | ||
|
Bubbliiiing
|
f26f0a809b | ||
|
Bubbliiiing
|
d7a37ef884 | ||
|
Bubbliiiing
|
cc609b4d87 | ||
|
Bubbliiiing
|
b0fe858bd6 | ||
|
Bubbliiiing
|
d11d6665bc | ||
|
Tianhao-Qi
|
7d91e1369c | ||
|
Bubbliiiing
|
7da0e755eb | ||
|
Bubbliiiing
|
5e2f7fcdac | ||
|
hkz
|
1fb0696fdc | ||
|
Tianhao-Qi
|
faa208e8d9 | ||
|
mohui37
|
3c19c391cd | ||
|
Tianhao-Qi
|
278a4c3cd2 | ||
|
Bubbliiiing
|
f25043496a | ||
|
Bubbliiiing
|
991e7cd2bd | ||
|
hkz
|
652b58f24c | ||
|
Bubbliiiing
|
f149dba611 | ||
|
|
8fd7a40698 | ||
|
Robin Huangandsnomiao
|
cea306d279 | ||
|
hkz
|
f865b60e0a | ||
|
hkzandbubbliiiing
|
09e7bd2bd0 | ||
|
Bubbliiiing
|
ae4f4187f7 | ||
|
Bubbliiiing
|
e90bc58da9 | ||
|
Bubbliiiing
|
821af5cf3b | ||
|
Bubbliiiing
|
10076a3aee | ||
|
Barak Karavani
|
f28461ed25 | ||
|
Bubbliiiingandhuangkunzhe.hkz
|
e1e7145c87 | ||
|
|
6c39567168 | ||
|
hkz
|
8efec19966 | ||
|
Ikko Eltociear Ashimine
|
b2cb4df5cc | ||
|
hkz
|
2114d906df | ||
|
hkz
|
0788cd4e8b | ||
|
bubbliiiing
|
c69357e4ea | ||
|
bubbliiiing
|
697e9749ce | ||
|
bubbliiiing
|
1f54ab9f78 | ||
|
Bubbliiiing
|
24f6209b6d | ||
|
yunkchen
|
4de9773025 | ||
|
Bubbliiiingand梧岚
|
2a93e5c14e | ||
|
hkz
|
2aa923b65c | ||
|
Bubbliiiing
|
67ef062b64 | ||
|
Bubbliiiingandyunkchen
|
0a9b013f39 | ||
|
Bubbliiiing
|
1b0e754e6c | ||
|
bubbliiiing
|
96c1df89e6 | ||
|
Wang Qiang
|
937bac68fb | ||
|
Wang Qiang
|
0323907db5 | ||
|
Wang Qiang
|
3544b5d8bf | ||
|
bubbliiiing
|
24973afceb | ||
|
bubbliiiing
|
2041d1aafc | ||
|
bubbliiiing
|
320d69a7c5 | ||
|
bubbliiiing
|
a492e2dfde | ||
|
bubbliiiing
|
811a56a977 | ||
|
bubbliiiing
|
d4d2a5c3c6 | ||
|
bubbliiiing
|
17682a058d | ||
|
bubbliiiing
|
4f647534be | ||
|
Bubbliiiing
|
7246858feb | ||
|
Bubbliiiing
|
2e8d316e6e |
@@ -0,0 +1,28 @@
|
||||
name: Publish to Comfy registry
|
||||
on:
|
||||
workflow_dispatch:
|
||||
push:
|
||||
branches:
|
||||
- main
|
||||
- master
|
||||
paths:
|
||||
- "pyproject.toml"
|
||||
|
||||
permissions:
|
||||
issues: write
|
||||
|
||||
jobs:
|
||||
publish-node:
|
||||
name: Publish Custom Node to registry
|
||||
runs-on: ubuntu-latest
|
||||
if: ${{ github.repository_owner == 'aigc-apps' }}
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
submodules: true
|
||||
- name: Publish Custom Node
|
||||
uses: Comfy-Org/publish-node-action@v1
|
||||
with:
|
||||
## Add your own personal access token to your Github Repository secrets and reference it here.
|
||||
personal_access_token: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
@@ -6,9 +6,12 @@ taming*
|
||||
samples*
|
||||
datasets*
|
||||
asset*
|
||||
_*
|
||||
logs*
|
||||
__pycache__/
|
||||
*.py[cod]
|
||||
*$py.class
|
||||
scripts_demo*
|
||||
|
||||
# C extensions
|
||||
*.so
|
||||
|
||||
@@ -0,0 +1,52 @@
|
||||
FROM nvidia/cuda:12.1.0-cudnn8-devel-ubuntu22.04
|
||||
ENV DEBIAN_FRONTEND noninteractive
|
||||
|
||||
RUN rm -r /etc/apt/sources.list.d/
|
||||
|
||||
RUN apt-get update -y && apt-get install -y \
|
||||
libgl1 libglib2.0-0 google-perftools \
|
||||
sudo wget git git-lfs vim tig pkg-config libcairo2-dev \
|
||||
aria2 telnet curl net-tools iputils-ping jq \
|
||||
python3-pip python-is-python3 python3.10-venv tzdata lsof zip tmux
|
||||
RUN apt-get update && \
|
||||
apt-get install -y software-properties-common && \
|
||||
add-apt-repository ppa:ubuntuhandbook1/ffmpeg6 && \
|
||||
apt-get update && \
|
||||
apt-get install -y ffmpeg
|
||||
|
||||
RUN pip3 install --upgrade pip -i https://mirrors.aliyun.com/pypi/simple/
|
||||
|
||||
# add all extensions
|
||||
RUN pip install wandb tqdm GitPython==3.1.32 Pillow==9.5.0 setuptools --upgrade -i https://mirrors.aliyun.com/pypi/simple/
|
||||
|
||||
RUN pip install torch==2.4.0 torchvision==0.19.0 torchaudio==2.4.0 --index-url https://download.pytorch.org/whl/cu118
|
||||
RUN pip install xformers==0.0.27.post2 --index-url https://download.pytorch.org/whl/cu118
|
||||
|
||||
# install vllm (video-caption)
|
||||
RUN pip install vllm==0.6.3
|
||||
|
||||
# install requirements (video-caption)
|
||||
WORKDIR /root/
|
||||
COPY easyanimate/video_caption/requirements.txt /root/requirements-video_caption.txt
|
||||
RUN pip install -r /root/requirements-video_caption.txt
|
||||
RUN rm /root/requirements-video_caption.txt
|
||||
|
||||
RUN pip install -U http://eas-data.oss-cn-shanghai.aliyuncs.com/sdk/allspark-0.15-py2.py3-none-any.whl
|
||||
RUN pip install -e git+https://github.com/CompVis/taming-transformers.git@master#egg=taming-transformers
|
||||
RUN pip install came-pytorch deepspeed pytorch_lightning==1.9.4 func_timeout -i https://mirrors.aliyun.com/pypi/simple/
|
||||
|
||||
# install requirements
|
||||
RUN pip install bitsandbytes mamba-ssm causal-conv1d>=1.4.0 -i https://mirrors.aliyun.com/pypi/simple/
|
||||
RUN pip install ipykernel -i https://mirrors.aliyun.com/pypi/simple/
|
||||
COPY ./requirements.txt /root/requirements.txt
|
||||
RUN pip install -r /root/requirements.txt -i https://mirrors.aliyun.com/pypi/simple/
|
||||
RUN rm -rf /root/requirements.txt
|
||||
|
||||
# install package patches (video-caption)
|
||||
COPY easyanimate/video_caption/package_patches/easyocr_detection_patched.py /usr/local/lib/python3.10/dist-packages/easyocr/detection.py
|
||||
COPY easyanimate/video_caption/package_patches/vila_siglip_encoder_patched.py /usr/local/lib/python3.10/dist-packages/llava/model/multimodal_encoder/siglip_encoder.py
|
||||
|
||||
ENV PYTHONUNBUFFERED 1
|
||||
ENV NVIDIA_DISABLE_REQUIRE 1
|
||||
|
||||
WORKDIR /root/
|
||||
@@ -1,45 +1,60 @@
|
||||
# CogVideoX-Fun
|
||||
# VideoX-Fun
|
||||
|
||||
😊 Welcome!
|
||||
|
||||
English | [简体中文](./README_zh-CN.md)
|
||||
CogVideoX-Fun:
|
||||
[](https://huggingface.co/spaces/alibaba-pai/CogVideoX-Fun-5b)
|
||||
|
||||
Wan-Fun:
|
||||
[](https://huggingface.co/spaces/alibaba-pai/Wan2.1-Fun-1.3B-InP)
|
||||
|
||||
English | [简体中文](./README_zh-CN.md) | [日本語](./README_ja-JP.md)
|
||||
|
||||
# Table of Contents
|
||||
- [Table of Contents](#table-of-contents)
|
||||
- [Introduction](#introduction)
|
||||
- [Quick Start](#quick-start)
|
||||
- [Video Result](#video-result)
|
||||
- [How to use](#how-to-use)
|
||||
- [Model zoo](#model-zoo)
|
||||
- [TODO List](#todo-list)
|
||||
- [Reference](#reference)
|
||||
- [License](#license)
|
||||
|
||||
# Introduction
|
||||
CogVideoX-Fun is a modified pipeline based on the CogVideoX structure, designed to provide more flexibility in generation. It can be used to create AI images and videos, as well as to train baseline models and Lora models for Diffusion Transformer. We support predictions directly from the already trained CogVideoX-Fun model, allowing the generation of videos at different resolutions, approximately 6 seconds long with 8 fps (1 to 49 frames). Users can also train their own baseline models and Lora models to achieve certain style transformations.
|
||||
VideoX-Fun is a video generation pipeline that can be used to generate AI images and videos, as well as to train baseline and Lora models for Diffusion Transformer. We support direct prediction from pre-trained baseline models to generate videos with different resolutions, durations, and FPS. Additionally, we also support users in training their own baseline and Lora models to perform specific style transformations.
|
||||
|
||||
We will support quick pull-ups from different platforms, refer to [Quick Start](#quick-start).
|
||||
|
||||
What's New:
|
||||
- Create code! Now supporting Windows and Linux. Supports video generation at any resolution from 256x256x49 to 1024x1024x49. [ 2024.09.09 ]
|
||||
- Added support for Wan 2.2 series models, Wan-VACE control model, Fantasy Talking digital human model, Qwen-Image, Flux image generation models, and more. [2025.10.16]
|
||||
- Update Wan2.1-Fun-V1.1: Support for 14B and 1.3B model Control + Reference Image models, support for camera control, and the Inpaint model has been retrained for improved performance. [2025.04.25]
|
||||
- Update Wan2.1-Fun-V1.0: Support I2V and Control models for 14B and 1.3B models, with support for start and end frame prediction. [2025.03.26]
|
||||
- Update CogVideoX-Fun-V1.5: Upload I2V model and related training/prediction code. [2024.12.16]
|
||||
- Reward Lora Support: Train Lora using reward backpropagation techniques to optimize generated videos, making them better aligned with human preferences. [More Information](scripts/README_TRAIN_REWARD.md). New version of the control model supports various control conditions such as Canny, Depth, Pose, MLSD, etc. [2024.11.21]
|
||||
- Diffusers Support: CogVideoX-Fun Control is now supported in diffusers. Thanks to [a-r-r-o-w](https://github.com/a-r-r-o-w) for contributing support in this [PR](https://github.com/huggingface/diffusers/pull/9671). Check out the [documentation](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cogvideox) for more details. [2024.10.16]
|
||||
- Update CogVideoX-Fun-V1.1: Retrain i2v model, add Noise to increase the motion amplitude of the video. Upload control model training code and Control model. [2024.09.29]
|
||||
- Update CogVideoX-Fun-V1.0: Initial code release! Now supports Windows and Linux. Supports video generation at arbitrary resolutions from 256x256x49 to 1024x1024x49 for 2B and 5B models. [2024.09.18]
|
||||
|
||||
Function:
|
||||
- [Data Preprocessing](#data-preprocess)
|
||||
- [Train DiT](#dit-train)
|
||||
- [Video Generation](#video-gen)
|
||||
|
||||
These are our generated results [GALLERY](scripts/Result_Gallery.md) (Click the image below to see the video):
|
||||
|
||||
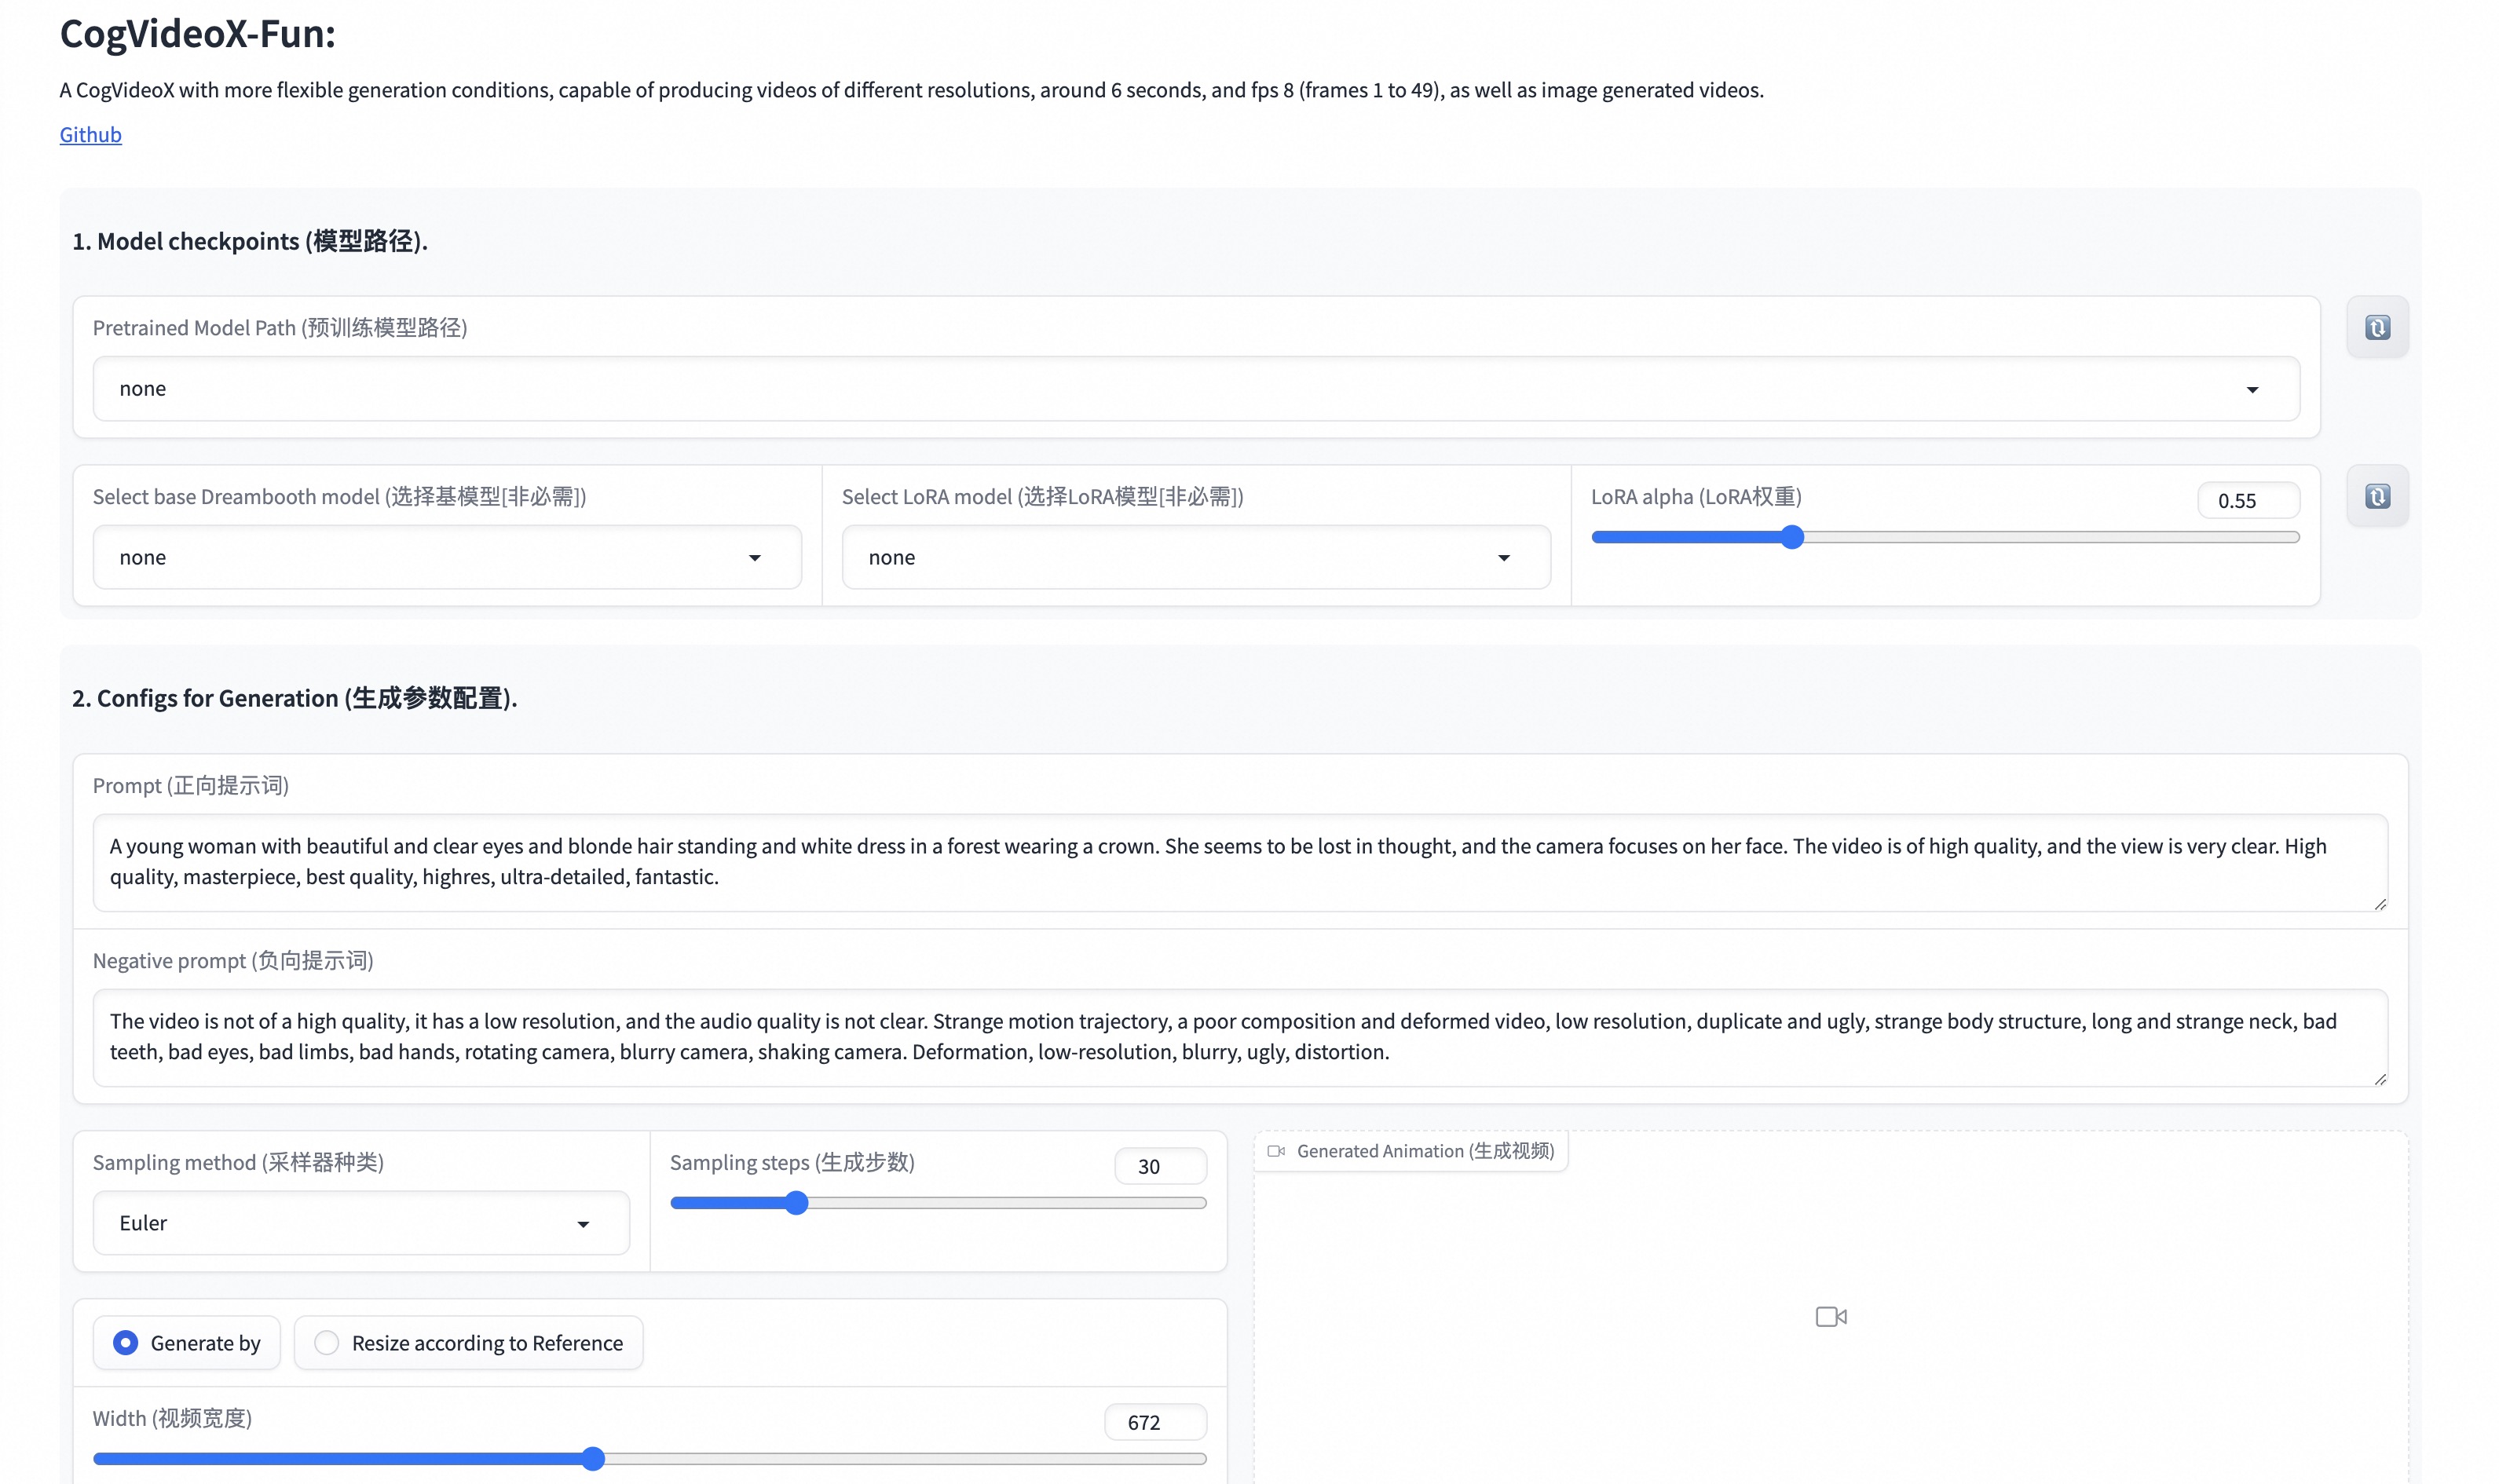
Our UI interface is as follows:
|
||||
|
||||
|
||||
# Quick Start
|
||||
### 1. Cloud usage: AliyunDSW/Docker
|
||||
#### a. From AliyunDSW
|
||||
On the way.
|
||||
DSW has free GPU time, which can be applied once by a user and is valid for 3 months after applying.
|
||||
|
||||
Aliyun provide free GPU time in [Freetier](https://free.aliyun.com/?product=9602825&crowd=enterprise&spm=5176.28055625.J_5831864660.1.e939154aRgha4e&scm=20140722.M_9974135.P_110.MO_1806-ID_9974135-MID_9974135-CID_30683-ST_8512-V_1), get it and use in Aliyun PAI-DSW to start CogVideoX-Fun within 5min!
|
||||
|
||||
[](https://gallery.pai-ml.com/#/preview/deepLearning/cv/cogvideox_fun)
|
||||
|
||||
#### b. From ComfyUI
|
||||
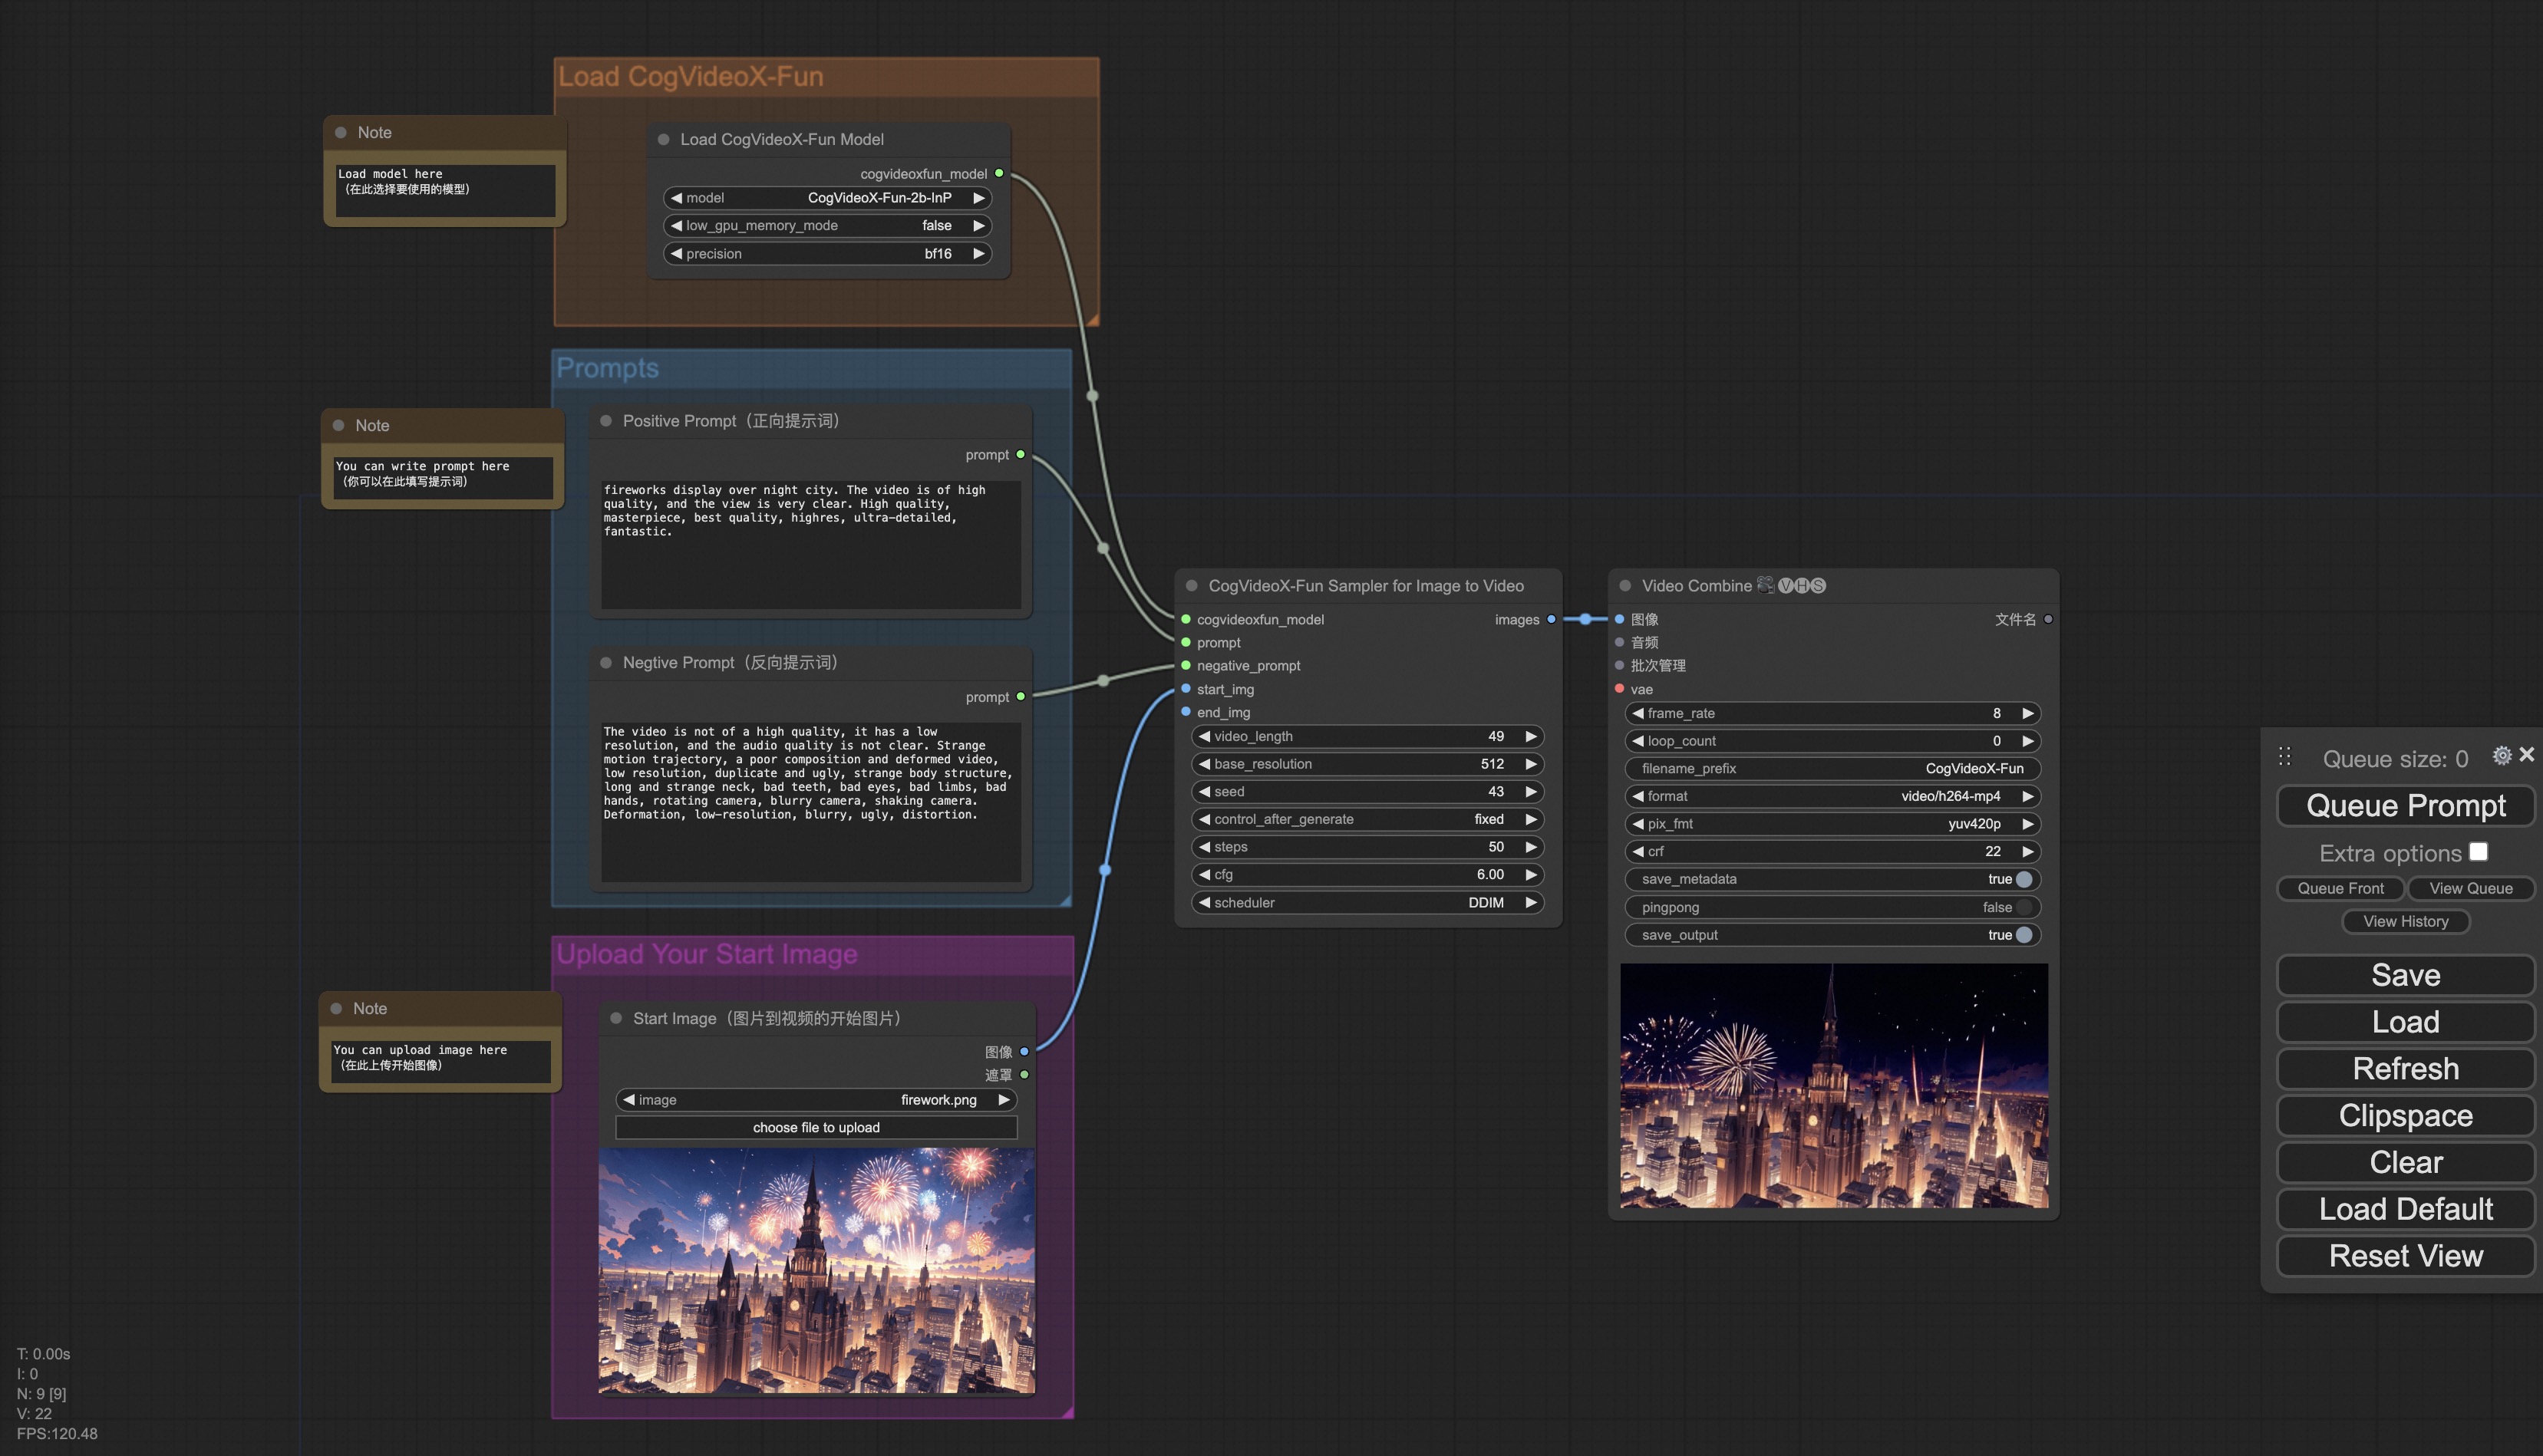
Our ComfyUI is as follows, please refer to [ComfyUI README](comfyui/README.md) for details.
|
||||

|
||||
|
||||
|
||||
#### c. From docker
|
||||
If you are using docker, please make sure that the graphics card driver and CUDA environment have been installed correctly in your machine.
|
||||
@@ -54,25 +69,28 @@ docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cud
|
||||
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# clone code
|
||||
git clone https://github.com/aigc-apps/CogVideoX-Fun.git
|
||||
git clone https://github.com/aigc-apps/VideoX-Fun.git
|
||||
|
||||
# enter CogVideoX-Fun's dir
|
||||
cd CogVideoX-Fun
|
||||
# enter VideoX-Fun's dir
|
||||
cd VideoX-Fun
|
||||
|
||||
# download weights
|
||||
mkdir models/Diffusion_Transformer
|
||||
mkdir models/Personalized_Model
|
||||
|
||||
wget https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz -O models/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz
|
||||
# Please use the hugginface link or modelscope link to download the model.
|
||||
# CogVideoX-Fun
|
||||
# https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP
|
||||
# https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP
|
||||
|
||||
cd models/Diffusion_Transformer/
|
||||
tar -xvf CogVideoX-Fun-2b-InP.tar.gz
|
||||
cd ../../
|
||||
# Wan
|
||||
# https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP
|
||||
# https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP
|
||||
```
|
||||
|
||||
### 2. Local install: Environment Check/Downloading/Installation
|
||||
#### a. Environment Check
|
||||
We have verified CogVideoX-Fun execution on the following environment:
|
||||
We have verified this repo execution on the following environment:
|
||||
|
||||
The detailed of Windows:
|
||||
- OS: Windows 10
|
||||
@@ -95,34 +113,358 @@ We need about 60GB available on disk (for saving weights), please check!
|
||||
#### b. Weights
|
||||
We'd better place the [weights](#model-zoo) along the specified path:
|
||||
|
||||
**Via ComfyUI**:
|
||||
Put the models into the ComfyUI weights folder `ComfyUI/models/Fun_Models/`:
|
||||
```
|
||||
📦 ComfyUI/
|
||||
├── 📂 models/
|
||||
│ └── 📂 Fun_Models/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
|
||||
│ ├── 📂 Wan2.1-Fun-14B-InP
|
||||
│ └── 📂 Wan2.1-Fun-1.3B-InP/
|
||||
```
|
||||
|
||||
**Run its own python file or UI interface**:
|
||||
```
|
||||
📦 models/
|
||||
├── 📂 Diffusion_Transformer/
|
||||
│ └── 📂 CogVideoX-Fun-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
|
||||
│ ├── 📂 Wan2.1-Fun-14B-InP
|
||||
│ └── 📂 Wan2.1-Fun-1.3B-InP/
|
||||
├── 📂 Personalized_Model/
|
||||
│ └── your trained trainformer model / your trained lora model (for UI load)
|
||||
```
|
||||
|
||||
# How to use
|
||||
# Video Result
|
||||
|
||||
<h3 id="video-gen">1. Inference </h3>
|
||||
### Wan2.1-Fun-V1.1-14B-InP && Wan2.1-Fun-V1.1-1.3B-InP
|
||||
|
||||
#### a. Using Python Code
|
||||
- Step 1: Download the corresponding [weights](#model-zoo) and place them in the models folder.
|
||||
- Step 2: Modify prompt, neg_prompt, guidance_scale, and seed in the predict_t2v.py file.
|
||||
- Step 3: Run the predict_t2v.py file, wait for the generated results, and save the results in the samples/cogvideox-fun-videos-t2v folder.
|
||||
- Step 4: If you want to combine other backbones you have trained with Lora, modify the predict_t2v.py and Lora_path in predict_t2v.py depending on the situation.
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
#### b. Using webui
|
||||
- Step 1: Download the corresponding [weights](#model-zoo) and place them in the models folder.
|
||||
- Step 2: Run the app.py file to enter the graph page.
|
||||
- Step 3: Select the generated model based on the page, fill in prompt, neg_prompt, guidance_scale, and seed, click on generate, wait for the generated result, and save the result in the samples folder.
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
#### c. From ComfyUI
|
||||
Please refer to [ComfyUI README](comfyui/README.md) for details.
|
||||
### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
|
||||
|
||||
Generic Control Video + Reference Image:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Reference Image
|
||||
</td>
|
||||
<td>
|
||||
Control Video
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-14B-Control
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-1.3B-Control
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</table>
|
||||
|
||||
|
||||
Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</table>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Pan Up
|
||||
</td>
|
||||
<td>
|
||||
Pan Left
|
||||
</td>
|
||||
<td>
|
||||
Pan Right
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
Pan Down
|
||||
</td>
|
||||
<td>
|
||||
Pan Up + Pan Left
|
||||
</td>
|
||||
<td>
|
||||
Pan Up + Pan Right
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B
|
||||
|
||||
Resolution-1024
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
Resolution-768
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
Resolution-512
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B-Control
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
A young woman with beautiful clear eyes and blonde hair, wearing white clothes and twisting her body, with the camera focused on her face. High quality, masterpiece, best quality, high resolution, ultra-fine, dreamlike.
|
||||
</td>
|
||||
<td>
|
||||
A young woman with beautiful clear eyes and blonde hair, wearing white clothes and twisting her body, with the camera focused on her face. High quality, masterpiece, best quality, high resolution, ultra-fine, dreamlike.
|
||||
</td>
|
||||
<td>
|
||||
A young bear.
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
# How to Use
|
||||
|
||||
<h3 id="video-gen">1. Generation</h3>
|
||||
|
||||
#### a. GPU Memory Optimization
|
||||
Since Wan2.1 has a very large number of parameters, we need to consider memory optimization strategies to adapt to consumer-grade GPUs. We provide `GPU_memory_mode` for each prediction file, allowing you to choose between `model_cpu_offload`, `model_cpu_offload_and_qfloat8`, and `sequential_cpu_offload`. This solution is also applicable to CogVideoX-Fun generation.
|
||||
|
||||
- `model_cpu_offload`: The entire model is moved to the CPU after use, saving some GPU memory.
|
||||
- `model_cpu_offload_and_qfloat8`: The entire model is moved to the CPU after use, and the transformer model is quantized to float8, saving more GPU memory.
|
||||
- `sequential_cpu_offload`: Each layer of the model is moved to the CPU after use. It is slower but saves a significant amount of GPU memory.
|
||||
|
||||
`qfloat8` may slightly reduce model performance but saves more GPU memory. If you have sufficient GPU memory, it is recommended to use `model_cpu_offload`.
|
||||
|
||||
#### b. Using ComfyUI
|
||||
For details, refer to [ComfyUI README](comfyui/README.md).
|
||||
|
||||
#### c. Running Python Files
|
||||
|
||||
##### i. Single-GPU Inference:
|
||||
|
||||
- **Step 1**: Download the corresponding [weights](#model-zoo) and place them in the `models` folder.
|
||||
- **Step 2**: Use different files for prediction based on the weights and prediction goals. This library currently supports CogVideoX-Fun, Wan2.1, and Wan2.1-Fun. Different models are distinguished by folder names under the `examples` folder, and their supported features vary. Use them accordingly. Below is an example using CogVideoX-Fun:
|
||||
- **Text-to-Video**:
|
||||
- Modify `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_t2v.py`.
|
||||
- Run the file `examples/cogvideox_fun/predict_t2v.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos`.
|
||||
- **Image-to-Video**:
|
||||
- Modify `validation_image_start`, `validation_image_end`, `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_i2v.py`.
|
||||
- `validation_image_start` is the starting image of the video, and `validation_image_end` is the ending image of the video.
|
||||
- Run the file `examples/cogvideox_fun/predict_i2v.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos_i2v`.
|
||||
- **Video-to-Video**:
|
||||
- Modify `validation_video`, `validation_image_end`, `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_v2v.py`.
|
||||
- `validation_video` is the reference video for video-to-video generation. You can use the following demo video: [Demo Video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/play_guitar.mp4).
|
||||
- Run the file `examples/cogvideox_fun/predict_v2v.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos_v2v`.
|
||||
- **Controlled Video Generation (Canny, Pose, Depth, etc.)**:
|
||||
- Modify `control_video`, `validation_image_end`, `prompt`, `neg_prompt`, `guidance_scale`, and `seed` in the file `examples/cogvideox_fun/predict_v2v_control.py`.
|
||||
- `control_video` is the control video extracted using operators such as Canny, Pose, or Depth. You can use the following demo video: [Demo Video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/pose.mp4).
|
||||
- Run the file `examples/cogvideox_fun/predict_v2v_control.py` and wait for the results. The generated videos will be saved in the folder `samples/cogvideox-fun-videos_v2v_control`.
|
||||
- **Step 3**: If you want to integrate other backbones or Loras trained by yourself, modify `lora_path` and relevant paths in `examples/{model_name}/predict_t2v.py` or `examples/{model_name}/predict_i2v.py` as needed.
|
||||
|
||||
##### ii. Multi-GPU Inference:
|
||||
When using multi-GPU inference, please make sure to install the xfuser. We recommend installing xfuser==0.4.2 and yunchang==0.6.2.
|
||||
```
|
||||
pip install xfuser==0.4.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
pip install yunchang==0.6.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
```
|
||||
|
||||
Please ensure that the product of `ulysses_degree` and `ring_degree` equals the number of GPUs being used. For example, if you are using 8 GPUs, you can set `ulysses_degree=2` and `ring_degree=4`, or alternatively `ulysses_degree=4` and `ring_degree=2`.
|
||||
|
||||
- `ulysses_degree` performs parallelization after splitting across the heads.
|
||||
- `ring_degree` performs parallelization after splitting across the sequence.
|
||||
|
||||
Compared to `ulysses_degree`, `ring_degree` incurs higher communication costs. Therefore, when setting these parameters, you should take into account both the sequence length and the number of heads in the model.
|
||||
|
||||
Let’s take 8-GPU parallel inference as an example:
|
||||
|
||||
- **For Wan2.1-Fun-V1.1-14B-InP**, which has 40 heads, `ulysses_degree` should be set to a divisor of 40 (e.g., 2, 4, 8, etc.). Thus, when using 8 GPUs for parallel inference, you can set `ulysses_degree=8` and `ring_degree=1`.
|
||||
|
||||
- **For Wan2.1-Fun-V1.1-1.3B-InP**, which has 12 heads, `ulysses_degree` should be set to a divisor of 12 (e.g., 2, 4, etc.). Thus, when using 8 GPUs for parallel inference, you can set `ulysses_degree=4` and `ring_degree=2`.
|
||||
|
||||
After setting the parameters, run the following command for parallel inference:
|
||||
|
||||
```sh
|
||||
torchrun --nproc-per-node=8 examples/wan2.1_fun/predict_t2v.py
|
||||
```
|
||||
|
||||
#### d. Using the Web UI
|
||||
The web UI supports text-to-video, image-to-video, video-to-video, and controlled video generation (Canny, Pose, Depth, etc.). This library currently supports CogVideoX-Fun, Wan2.1, and Wan2.1-Fun. Different models are distinguished by folder names under the `examples` folder, and their supported features vary. Use them accordingly. Below is an example using CogVideoX-Fun:
|
||||
|
||||
- **Step 1**: Download the corresponding [weights](#model-zoo) and place them in the `models` folder.
|
||||
- **Step 2**: Run the file `examples/cogvideox_fun/app.py` to access the Gradio interface.
|
||||
- **Step 3**: Select the generation model on the page, fill in `prompt`, `neg_prompt`, `guidance_scale`, and `seed`, click "Generate," and wait for the results. The generated videos will be saved in the `sample` folder.
|
||||
|
||||
### 2. Model Training
|
||||
A complete CogVideoX-Fun training pipeline should include data preprocessing, and Video DiT training.
|
||||
A complete model training pipeline should include data preprocessing and Video DiT training. The training process for different models is similar, and the data formats are also similar:
|
||||
|
||||
<h4 id="data-preprocess">a. data preprocessing</h4>
|
||||
|
||||
@@ -179,7 +521,7 @@ You can also set the path as absolute path as follow:
|
||||
|
||||
<h4 id="dit-train">b. Video DiT training </h4>
|
||||
|
||||
If the data format is relative path during data preprocessing, please set ```scripts/train.sh``` as follow.
|
||||
If the data format is relative path during data preprocessing, please set ```scripts/{model_name}/train.sh``` as follow.
|
||||
```
|
||||
export DATASET_NAME="datasets/internal_datasets/"
|
||||
export DATASET_META_NAME="datasets/internal_datasets/json_of_internal_datasets.json"
|
||||
@@ -196,23 +538,170 @@ Then, we run scripts/train.sh.
|
||||
sh scripts/train.sh
|
||||
```
|
||||
|
||||
For details on setting some parameters, please refer to [Readme Train](scripts/README_TRAIN.md) and [Readme Lora](scripts/README_TRAIN_LORA.md).
|
||||
For details on some parameter settings:
|
||||
Wan2.1-Fun can be found in [Readme Train](scripts/wan2.1_fun/README_TRAIN.md) and [Readme Lora](scripts/wan2.1_fun/README_TRAIN_LORA.md).
|
||||
Wan2.1 can be found in [Readme Train](scripts/wan2.1/README_TRAIN.md) and [Readme Lora](scripts/wan2.1/README_TRAIN_LORA.md).
|
||||
CogVideoX-Fun can be found in [Readme Train](scripts/cogvideox_fun/README_TRAIN.md) and [Readme Lora](scripts/cogvideox_fun/README_TRAIN_LORA.md).
|
||||
|
||||
|
||||
# Model zoo
|
||||
## 1. Wan2.2-Fun
|
||||
|
||||
| Name | Storage Space | Url | Hugging Face | Description |
|
||||
| Name | Storage Size | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP.tar.gz | Before extraction:9.69 GB \/ After extraction: 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 144 frames at a rate of 24 frames per second. |
|
||||
| Wan2.2-Fun-A14B-InP | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-InP) | Wan2.2-Fun-14B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
|
||||
| Wan2.2-Fun-A14B-Control | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control)| Wan2.2-Fun-14B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support. |
|
||||
| Wan2.2-Fun-A14B-Control-Camera | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control-Camera)| Wan2.2-Fun-14B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
| Wan2.2-VACE-Fun-A14B | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-VACE-Fun-A14B) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-VACE-Fun-A14B) | Control weights for Wan2.2 trained using the VACE scheme (based on the base model Wan2.2-T2V-A14B), supporting various control conditions such as Canny, Depth, Pose, MLSD, trajectory control, etc. It supports video generation by specifying the subject. It supports multi-resolution (512, 768, 1024) video prediction, and is trained with 81 frames at 16 FPS. It also supports multi-language prediction. |
|
||||
| Wan2.2-Fun-5B-InP | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-InP) | Wan2.2-Fun-5B text-to-video weights trained at 121 frames, 24 FPS, supporting first/last frame prediction. |
|
||||
| Wan2.2-Fun-5B-Control | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control)| Wan2.2-Fun-5B video control weights, supporting control conditions like Canny, Depth, Pose, MLSD, and trajectory control. Trained at 121 frames, 24 FPS, with multilingual prediction support. |
|
||||
| Wan2.2-Fun-5B-Control-Camera | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control-Camera)| Wan2.2-Fun-5B camera lens control weights. Trained at 121 frames, 24 FPS, with multilingual prediction support. |
|
||||
|
||||
# TODO List
|
||||
- Support CogVideoX-5b.
|
||||
|
||||
## 2. Wan2.2
|
||||
|
||||
| Name | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|
|
||||
| Wan2.2-TI2V-5B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-TI2V-5B) | Wan2.2-5B Text-to-Video Weights |
|
||||
| Wan2.2-T2V-14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-T2V-A14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-T2V-A14B) | Wan2.2-14B Text-to-Video Weights |
|
||||
| Wan2.2-I2V-A14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-I2V-A14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-I2V-A14B) | Wan2.2-I2V-A14B Image-to-Video Weights |
|
||||
|
||||
## 3. Wan2.1-Fun
|
||||
|
||||
V1.1:
|
||||
| Name | Storage Size | Hugging Face | Model Scope | Description |
|
||||
|------|--------------|--------------|-------------|-------------|
|
||||
| Wan2.1-Fun-V1.1-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP) | Wan2.1-Fun-V1.1-1.3B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
|
||||
| Wan2.1-Fun-V1.1-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP) | Wan2.1-Fun-V1.1-14B text-to-video generation weights, trained at multiple resolutions, supports start-end image prediction. |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control) | Wan2.1-Fun-V1.1-1.3B video control weights support various control conditions such as Canny, Depth, Pose, MLSD, etc., supports reference image + control condition-based control, and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control) | Wan2.1-Fun-V1.1-14B video control weights support various control conditions such as Canny, Depth, Pose, MLSD, etc., supports reference image + control condition-based control, and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control-Camera | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control-Camera) | Wan2.1-Fun-V1.1-1.3B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
| Wan2.1-Fun-V1.1-14B-Control-Camera | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control-Camera) | Wan2.1-Fun-V1.1-14B camera lens control weights. Supports multi-resolution (512, 768, 1024) video prediction, trained with 81 frames at 16 FPS, supports multilingual prediction. |
|
||||
|
||||
V1.0:
|
||||
| Name | Storage Space | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-InP) | Wan2.1-Fun-1.3B text-to-video weights, trained at multiple resolutions, supporting start and end frame prediction. |
|
||||
| Wan2.1-Fun-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP) | Wan2.1-Fun-14B text-to-video weights, trained at multiple resolutions, supporting start and end frame prediction. |
|
||||
| Wan2.1-Fun-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-Control) | Wan2.1-Fun-1.3B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support. |
|
||||
| Wan2.1-Fun-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-Control) | Wan2.1-Fun-14B video control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc., and trajectory control. Supports multi-resolution (512, 768, 1024) video prediction at 81 frames, trained at 16 frames per second, with multilingual prediction support. |
|
||||
|
||||
## 4. Wan2.1
|
||||
|
||||
| Name | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|
|
||||
| Wan2.1-T2V-1.3B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-1.3B) | Wanxiang 2.1-1.3B text-to-video weights |
|
||||
| Wan2.1-T2V-14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-14B) | Wanxiang 2.1-14B text-to-video weights |
|
||||
| Wan2.1-I2V-14B-480P | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-480P) | Wanxiang 2.1-14B-480P image-to-video weights |
|
||||
| Wan2.1-I2V-14B-720P| [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | Wanxiang 2.1-14B-720P image-to-video weights |
|
||||
|
||||
## 5. FantasyTalking
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-I2V-14B-720P | - | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | Wan 2.1-14B-720P image-to-video model weights |
|
||||
| Wav2Vec | - | [🤗Link](https://huggingface.co/facebook/wav2vec2-base-960h) | [😄Link](https://modelscope.cn/models/AI-ModelScope/wav2vec2-base-960h) | Wav2Vec model; place inside the Wan2.1-I2V-14B-720P folder and rename to `audio_encoder` |
|
||||
| FantasyTalking model | - | [🤗Link](https://huggingface.co/acvlab/FantasyTalking/) | [😄Link](https://www.modelscope.cn/models/amap_cvlab/FantasyTalking/) | Official audio-conditioned weights |
|
||||
|
||||
## 6. Qwen-Image
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image | [🤗Link](https://huggingface.co/Qwen/Qwen-Image) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image) | Official Qwen-Image weights |
|
||||
| Qwen-Image-Edit | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit) | Official Qwen-Image-Edit weights |
|
||||
| Qwen-Image-Edit-2509 | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit-2509) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509) | Official Qwen-Image-Edit-2509 weights |
|
||||
|
||||
## 7. Qwen-Image-Fun
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image-2512-Fun-Controlnet-Union | - | [🤗Link](https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union) | [😄Link](https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union) | ControlNet weights for Qwen-Image-2512, supporting multiple control conditions such as Canny, Depth, Pose, MLSD, Scribble, etc. |
|
||||
|
||||
## 8. Z-Image
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image | [🤗Link](https://huggingface.co/Tongyi-MAI/Z-Image) | [😄Link](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image) | Official weights for Z-Image |
|
||||
| Z-Image-Turbo | [🤗Link](https://huggingface.co/Tongyi-MAI/Z-Image-Turbo) | [😄Link](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo) | Official weights for Z-Image-Turbo |
|
||||
|
||||
## 9. Z-Image-Fun
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image-Fun-Controlnet-Union-2.1 | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1) | ControlNet weights for Z-Image. Compared to the first version, it adds to more layers and has been trained for a longer period. It supports multiple control conditions including Canny, Depth, Pose, MLSD, Scribble and Gray. |
|
||||
| Z-Image-Fun-Lora-Distill | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill) | This is a Distill LoRA for Z-Image that distills both steps and CFG. This model does not require CFG and uses 8 steps for inference. |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union) | ControlNet weights for Z-Image-Turbo, supporting multiple control conditions such as Canny, Depth, Pose, MLSD, etc. |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union-2.1 | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | ControlNet weights for Z-Image-Turbo. Compared to the first version, it adds to more layers and has been trained for a longer period. It supports multiple control conditions including Canny, Depth, Pose, MLSD, and more. |
|
||||
|
||||
## 10. Flux
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| FLUX.1-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.1-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev) | Official FLUX.1-dev weights |
|
||||
| FLUX.2-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.2-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev) | Official FLUX.2-dev weights |
|
||||
|
||||
## 11. Flux-Fun
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| Flux.2-dev-Fun-Controlnet-Union | - | [🤗Link](https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union) | [😄Link](https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union) | Flux.2-dev control weights, supporting various control conditions such as Canny, Depth, Pose, MLSD, etc. |
|
||||
|
||||
## 12. HunyuanVideo
|
||||
|
||||
| Name | Storage | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| HunyuanVideo | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo) | - | HunyuanVideo-diffusers weights |
|
||||
| HunyuanVideo-I2V | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo-I2V) | - | HunyuanVideo-I2V-diffusers weights |
|
||||
|
||||
## 13. CogVideoX-Fun
|
||||
|
||||
V1.5:
|
||||
|
||||
| Name | Storage Space | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.5-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-5b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024) and has been trained on 85 frames at a rate of 8 frames per second. |
|
||||
| CogVideoX-Fun-V1.5-Reward-LoRAs | - | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs) | The official reward backpropagation technology model optimizes the videos generated by CogVideoX-Fun-V1.5 to better match human preferences. |
|
||||
|
||||
V1.1:
|
||||
|
||||
| Name | Storage Space | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.1-2b-InP | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. |
|
||||
| CogVideoX-Fun-V1.1-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Noise has been added to the reference image, and the amplitude of motion is greater compared to V1.0. |
|
||||
| CogVideoX-Fun-V1.1-2b-Pose | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Pose) | Our official pose-control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second.|
|
||||
| CogVideoX-Fun-V1.1-2b-Control | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Control) | Our official control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Supporting various control conditions such as Canny, Depth, Pose, MLSD, etc.|
|
||||
| CogVideoX-Fun-V1.1-5b-Pose | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Pose) | Our official pose-control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second.|
|
||||
| CogVideoX-Fun-V1.1-5b-Control | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Control) | Our official control video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. Supporting various control conditions such as Canny, Depth, Pose, MLSD, etc.|
|
||||
| CogVideoX-Fun-V1.1-Reward-LoRAs | - | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-Reward-LoRAs) | The official reward backpropagation technology model optimizes the videos generated by CogVideoX-Fun-V1.1 to better match human preferences. |
|
||||
|
||||
<details>
|
||||
<summary>(Obsolete) V1.0:</summary>
|
||||
|
||||
| Name | Storage Space | Hugging Face | Model Scope | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-2b-InP) | Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. |
|
||||
| CogVideoX-Fun-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP)| [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-5b-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 49 frames at a rate of 8 frames per second. |
|
||||
</details>
|
||||
|
||||
# Reference
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
|
||||
- Wan2.1: https://github.com/Wan-Video/Wan2.1/
|
||||
- Wan2.2: https://github.com/Wan-Video/Wan2.2/
|
||||
- Diffusers: https://github.com/huggingface/diffusers
|
||||
- Qwen-Image: https://github.com/QwenLM/Qwen-Image
|
||||
- Self-Forcing: https://github.com/guandeh17/Self-Forcing
|
||||
- Flux: https://github.com/black-forest-labs/flux
|
||||
- Flux2: https://github.com/black-forest-labs/flux2
|
||||
- HunyuanVideo: https://github.com/Tencent-Hunyuan/HunyuanVideo
|
||||
- ComfyUI-KJNodes: https://github.com/kijai/ComfyUI-KJNodes
|
||||
- ComfyUI-EasyAnimateWrapper: https://github.com/kijai/ComfyUI-EasyAnimateWrapper
|
||||
- ComfyUI-CameraCtrl-Wrapper: https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper
|
||||
- CameraCtrl: https://github.com/hehao13/CameraCtrl
|
||||
|
||||
# License
|
||||
This project is licensed under the [Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE).
|
||||
|
||||
The CogVideoX-2B model (including its corresponding Transformers module and VAE module) is released under the [Apache 2.0 License](LICENSE).
|
||||
The CogVideoX-2B model (including its corresponding Transformers module and VAE module) is released under the [Apache 2.0 License](LICENSE).
|
||||
|
||||
The CogVideoX-5B model (Transformers module) is released under the [CogVideoX LICENSE](https://huggingface.co/THUDM/CogVideoX-5b/blob/main/LICENSE).
|
||||
|
||||
@@ -0,0 +1,707 @@
|
||||
# VideoX-Fun
|
||||
|
||||
😊 ようこそ!
|
||||
|
||||
CogVideoX-Fun:
|
||||
[](https://huggingface.co/spaces/alibaba-pai/CogVideoX-Fun-5b)
|
||||
|
||||
Wan-Fun:
|
||||
[](https://huggingface.co/spaces/alibaba-pai/Wan2.1-Fun-1.3B-InP)
|
||||
|
||||
[English](./README.md) | [简体中文](./README_zh-CN.md) | 日本語
|
||||
|
||||
# 目次
|
||||
- [目次](#目次)
|
||||
- [紹介](#紹介)
|
||||
- [クイックスタート](#クイックスタート)
|
||||
- [ビデオ結果](#ビデオ結果)
|
||||
- [使用方法](#使用方法)
|
||||
- [モデルの場所](#モデルの場所)
|
||||
- [参考文献](#参考文献)
|
||||
- [ライセンス](#ライセンス)
|
||||
|
||||
# 紹介
|
||||
VideoX-Funはビデオ生成のパイプラインであり、AI画像やビデオの生成、Diffusion TransformerのベースラインモデルとLoraモデルのトレーニングに使用できます。我々は、すでに学習済みのベースラインモデルから直接予測を行い、異なる解像度、秒数、FPSのビデオを生成することをサポートしています。また、ユーザーが独自のベースラインモデルやLoraモデルをトレーニングし、特定のスタイル変換を行うこともサポートしています。
|
||||
|
||||
異なるプラットフォームからのクイックスタートをサポートします。詳細は[クイックスタート](#クイックスタート)を参照してください。
|
||||
|
||||
新機能:
|
||||
- Wan 2.2シリーズモデル、Wan-VACE制御モデル、Fantasy Talkingデジタルヒューマンモデル、Qwen-Image、Flux画像生成モデルなどのサポートを追加しました。[2025.10.16]
|
||||
- Wan2.1-Fun-V1.1バージョンを更新:14Bと1.3BモデルのControl+参照画像モデルをサポート、カメラ制御にも対応。さらに、Inpaintモデルを再訓練し、性能が向上しました。[2025.04.25]
|
||||
- Wan2.1-Fun-V1.0の更新:14Bおよび1.3BのI2V(画像からビデオ)モデルとControlモデルをサポートし、開始フレームと終了フレームの予測に対応。[2025.03.26]
|
||||
- CogVideoX-Fun-V1.5の更新:I2Vモデルと関連するトレーニング・予測コードをアップロード。[2024.12.16]
|
||||
- 報酬Loraのサポート:報酬逆伝播技術を使用してLoraをトレーニングし、生成された動画を最適化し、人間の好みによりよく一致させる。[詳細情報](scripts/README_TRAIN_REWARD.md)。新しいバージョンの制御モデルでは、Canny、Depth、Pose、MLSDなどの異なる制御条件に対応。[2024.11.21]
|
||||
- diffusersのサポート:CogVideoX-Fun Controlがdiffusersでサポートされるようになりました。[a-r-r-o-w](https://github.com/a-r-r-o-w)がこの[PR](https://github.com/huggingface/diffusers/pull/9671)でサポートを提供してくれたことに感謝します。詳細は[ドキュメント](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cogvideox)をご覧ください。[2024.10.16]
|
||||
- CogVideoX-Fun-V1.1の更新:i2vモデルを再トレーニングし、Noiseを追加して動画の動きの範囲を拡大。制御モデルのトレーニングコードとControlモデルをアップロード。[2024.09.29]
|
||||
- CogVideoX-Fun-V1.0の更新:コードを作成!WindowsとLinuxに対応しました。2Bおよび5Bモデルでの最大256x256x49から1024x1024x49までの任意の解像度の動画生成をサポート。[2024.09.18]
|
||||
|
||||
機能:
|
||||
- [データ前処理](#data-preprocess)
|
||||
- [DiTのトレーニング](#dit-train)
|
||||
- [ビデオ生成](#video-gen)
|
||||
|
||||
私たちのUIインターフェースは次のとおりです:
|
||||

|
||||
|
||||
# クイックスタート
|
||||
### 1. クラウド使用: AliyunDSW/Docker
|
||||
#### a. AliyunDSWから
|
||||
DSWには無料のGPU時間があり、ユーザーは一度申請でき、申請後3か月間有効です。
|
||||
|
||||
Aliyunは[Freetier](https://free.aliyun.com/?product=9602825&crowd=enterprise&spm=5176.28055625.J_5831864660.1.e939154aRgha4e&scm=20140722.M_9974135.P_110.MO_1806-ID_9974135-MID_9974135-CID_30683-ST_8512-V_1)で無料のGPU時間を提供しています。取得してAliyun PAI-DSWで使用し、5分以内にCogVideoX-Funを開始できます!
|
||||
|
||||
[](https://gallery.pai-ml.com/#/preview/deepLearning/cv/cogvideox_fun)
|
||||
|
||||
#### b. ComfyUIから
|
||||
私たちのComfyUIは次のとおりです。詳細は[ComfyUI README](comfyui/README.md)を参照してください。
|
||||

|
||||
|
||||
#### c. Dockerから
|
||||
Dockerを使用する場合、マシンにグラフィックスカードドライバとCUDA環境が正しくインストールされていることを確認してください。
|
||||
|
||||
次のコマンドをこの方法で実行します:
|
||||
|
||||
```
|
||||
# イメージをプル
|
||||
docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# イメージに入る
|
||||
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# コードをクローン
|
||||
git clone https://github.com/aigc-apps/VideoX-Fun.git
|
||||
|
||||
# VideoX-Funのディレクトリに入る
|
||||
cd VideoX-Fun
|
||||
|
||||
# 重みをダウンロード
|
||||
mkdir models/Diffusion_Transformer
|
||||
mkdir models/Personalized_Model
|
||||
|
||||
# Please use the hugginface link or modelscope link to download the model.
|
||||
# CogVideoX-Fun
|
||||
# https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP
|
||||
# https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP
|
||||
|
||||
# Wan
|
||||
# https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP
|
||||
# https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP
|
||||
```
|
||||
|
||||
### 2. ローカルインストール: 環境チェック/ダウンロード/インストール
|
||||
#### a. 環境チェック
|
||||
以下の環境でこのライブラリの実行を確認しています:
|
||||
|
||||
Windowsの詳細:
|
||||
- OS: Windows 10
|
||||
- python: python3.10 & python3.11
|
||||
- pytorch: torch2.2.0
|
||||
- CUDA: 11.8 & 12.1
|
||||
- CUDNN: 8+
|
||||
- GPU: Nvidia-3060 12G & Nvidia-3090 24G
|
||||
|
||||
Linuxの詳細:
|
||||
- OS: Ubuntu 20.04, CentOS
|
||||
- python: python3.10 & python3.11
|
||||
- pytorch: torch2.2.0
|
||||
- CUDA: 11.8 & 12.1
|
||||
- CUDNN: 8+
|
||||
- GPU:Nvidia-V100 16G & Nvidia-A10 24G & Nvidia-A100 40G & Nvidia-A100 80G
|
||||
|
||||
重みを保存するために約60GBのディスクスペースが必要です。確認してください!
|
||||
|
||||
#### b. 重み
|
||||
[重み](#model-zoo)を指定されたパスに配置することをお勧めします:
|
||||
|
||||
**ComfyUIを通じて**:
|
||||
モデルをComfyUIの重みフォルダ `ComfyUI/models/Fun_Models/` に入れます:
|
||||
```
|
||||
📦 ComfyUI/
|
||||
├── 📂 models/
|
||||
│ └── 📂 Fun_Models/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
|
||||
│ ├── 📂 Wan2.1-Fun-V1.1-14B-InP
|
||||
│ └── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
|
||||
```
|
||||
|
||||
**独自のpythonファイルまたはUIインターフェースを実行**:
|
||||
```
|
||||
📦 models/
|
||||
├── 📂 Diffusion_Transformer/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
|
||||
│ ├── 📂 Wan2.1-Fun-V1.1-14B-InP
|
||||
│ └── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
|
||||
├── 📂 Personalized_Model/
|
||||
│ └── あなたのトレーニング済みのトランスフォーマーモデル / あなたのトレーニング済みのLoraモデル(UIロード用)
|
||||
```
|
||||
|
||||
# ビデオ結果
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-InP && Wan2.1-Fun-V1.1-1.3B-InP
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
|
||||
|
||||
Generic Control Video + Reference Image:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Reference Image
|
||||
</td>
|
||||
<td>
|
||||
Control Video
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-14B-Control
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-1.3B-Control
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</table>
|
||||
|
||||
|
||||
Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</table>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Pan Up
|
||||
</td>
|
||||
<td>
|
||||
Pan Left
|
||||
</td>
|
||||
<td>
|
||||
Pan Right
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
Pan Down
|
||||
</td>
|
||||
<td>
|
||||
Pan Up + Pan Left
|
||||
</td>
|
||||
<td>
|
||||
Pan Up + Pan Right
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B
|
||||
|
||||
解像度-1024
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
解像度-768
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
解像度-512
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B-Control
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
美しい澄んだ目と金髪の若い女性が白い服を着て体をひねり、カメラは彼女の顔に焦点を合わせています。高品質、傑作、最高品質、高解像度、超微細、夢のような。
|
||||
</td>
|
||||
<td>
|
||||
美しい澄んだ目と金髪の若い女性が白い服を着て体をひねり、カメラは彼女の顔に焦点を合わせています。高品質、傑作、最高品質、高解像度、超微細、夢のような。
|
||||
</td>
|
||||
<td>
|
||||
若いクマ。
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
# 使い方
|
||||
|
||||
<h3 id="video-gen">1. 生成</h3>
|
||||
|
||||
#### a. GPUメモリ節約方法
|
||||
Wan2.1のパラメータが非常に大きいため、GPUメモリを節約し、コンシューマー向けGPUに適応させる必要があります。各予測ファイルには`GPU_memory_mode`を提供しており、`model_cpu_offload`、`model_cpu_offload_and_qfloat8`、`sequential_cpu_offload`の中から選択できます。この方法はCogVideoX-Funの生成にも適用されます。
|
||||
|
||||
- `model_cpu_offload`: モデル全体が使用後にCPUに移動し、一部のGPUメモリを節約します。
|
||||
- `model_cpu_offload_and_qfloat8`: モデル全体が使用後にCPUに移動し、Transformerモデルに対してfloat8の量子化を行い、より多くのGPUメモリを節約します。
|
||||
- `sequential_cpu_offload`: モデルの各層が使用後にCPUに移動します。速度は遅くなりますが、大量のGPUメモリを節約します。
|
||||
|
||||
`qfloat8`はモデルの性能を部分的に低下させる可能性がありますが、より多くのGPUメモリを節約できます。十分なGPUメモリがある場合は、`model_cpu_offload`の使用をお勧めします。
|
||||
|
||||
#### b. ComfyUIを使用する
|
||||
詳細は[ComfyUI README](comfyui/README.md)をご覧ください。
|
||||
|
||||
#### c. Pythonファイルを実行する
|
||||
|
||||
##### i. 単一GPUでの推論:
|
||||
|
||||
- ステップ1: 対応する[重み](#model-zoo)をダウンロードし、`models`フォルダに配置します。
|
||||
- ステップ2: 異なる重みと予測目標に基づいて、異なるファイルを使用して予測を行います。現在、このライブラリはCogVideoX-Fun、Wan2.1、およびWan2.1-Funをサポートしています。`examples`フォルダ内のフォルダ名で区別され、異なるモデルがサポートする機能が異なりますので、状況に応じて区別してください。以下はCogVideoX-Funを例として説明します。
|
||||
- テキストからビデオ:
|
||||
- `examples/cogvideox_fun/predict_t2v.py`ファイルで`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- 次に、`examples/cogvideox_fun/predict_t2v.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos`フォルダに保存されます。
|
||||
- 画像からビデオ:
|
||||
- `examples/cogvideox_fun/predict_i2v.py`ファイルで`validation_image_start`、`validation_image_end`、`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- `validation_image_start`はビデオの開始画像、`validation_image_end`はビデオの終了画像です。
|
||||
- 次に、`examples/cogvideox_fun/predict_i2v.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos_i2v`フォルダに保存されます。
|
||||
- ビデオからビデオ:
|
||||
- `examples/cogvideox_fun/predict_v2v.py`ファイルで`validation_video`、`validation_image_end`、`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- `validation_video`はビデオ生成のための参照ビデオです。以下のデモビデオを使用して実行できます:[デモビデオ](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/play_guitar.mp4)
|
||||
- 次に、`examples/cogvideox_fun/predict_v2v.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos_v2v`フォルダに保存されます。
|
||||
- 通常の制御付きビデオ生成(Canny、Pose、Depthなど):
|
||||
- `examples/cogvideox_fun/predict_v2v_control.py`ファイルで`control_video`、`validation_image_end`、`prompt`、`neg_prompt`、`guidance_scale`、`seed`を変更します。
|
||||
- `control_video`は、Canny、Pose、Depthなどの演算子で抽出された制御用ビデオです。以下のデモビデオを使用して実行できます:[デモビデオ](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/pose.mp4)
|
||||
- 次に、`examples/cogvideox_fun/predict_v2v_control.py`ファイルを実行し、結果が生成されるのを待ちます。結果は`samples/cogvideox-fun-videos_v2v_control`フォルダに保存されます。
|
||||
- ステップ3: 自分でトレーニングした他のバックボーンやLoraを組み合わせたい場合は、必要に応じて`examples/{model_name}/predict_t2v.py`や`examples/{model_name}/predict_i2v.py`、`lora_path`を修正します。
|
||||
|
||||
##### ii. 複数GPUでの推論:
|
||||
多カードでの推論を行う際は、xfuserリポジトリのインストールに注意してください。xfuser==0.4.2 と yunchang==0.6.2 のインストールが推奨されます。
|
||||
```
|
||||
pip install xfuser==0.4.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
pip install yunchang==0.6.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
```
|
||||
|
||||
`ulysses_degree` と `ring_degree` の積が使用する GPU 数と一致することを確認してください。たとえば、8つのGPUを使用する場合、`ulysses_degree=2` と `ring_degree=4`、または `ulysses_degree=4` と `ring_degree=2` を設定することができます。
|
||||
|
||||
- `ulysses_degree` はヘッド(head)に分割した後の並列化を行います。
|
||||
- `ring_degree` はシーケンスに分割した後の並列化を行います。
|
||||
|
||||
`ring_degree` は `ulysses_degree` よりも通信コストが高いため、これらのパラメータを設定する際には、シーケンス長とモデルのヘッド数を考慮する必要があります。
|
||||
|
||||
8GPUでの並列推論を例に挙げます:
|
||||
|
||||
- **Wan2.1-Fun-V1.1-14B-InP** はヘッド数が40あります。この場合、`ulysses_degree` は40で割り切れる値(例:2, 4, 8など)に設定する必要があります。したがって、8GPUを使用して並列推論を行う場合、`ulysses_degree=8` と `ring_degree=1` を設定できます。
|
||||
|
||||
- **Wan2.1-Fun-V1.1-1.3B-InP** はヘッド数が12あります。この場合、`ulysses_degree` は12で割り切れる値(例:2, 4など)に設定する必要があります。したがって、8GPUを使用して並列推論を行う場合、`ulysses_degree=4` と `ring_degree=2` を設定できます。
|
||||
|
||||
パラメータの設定が完了したら、以下のコマンドで並列推論を実行してください:
|
||||
|
||||
```sh
|
||||
torchrun --nproc-per-node=8 examples/wan2.1_fun/predict_t2v.py
|
||||
```
|
||||
|
||||
#### d. UIインターフェースを使用する
|
||||
|
||||
WebUIは、テキストからビデオ、画像からビデオ、ビデオからビデオ、および通常の制御付きビデオ生成(Canny、Pose、Depthなど)をサポートします。現在、このライブラリはCogVideoX-Fun、Wan2.1、およびWan2.1-Funをサポートしており、`examples`フォルダ内のフォルダ名で区別されています。異なるモデルがサポートする機能が異なるため、状況に応じて区別してください。以下はCogVideoX-Funを例として説明します。
|
||||
|
||||
- ステップ1: 対応する[重み](#model-zoo)をダウンロードし、`models`フォルダに配置します。
|
||||
- ステップ2: `examples/cogvideox_fun/app.py`ファイルを実行し、Gradioページに入ります。
|
||||
- ステップ3: ページ上で生成モデルを選択し、`prompt`、`neg_prompt`、`guidance_scale`、`seed`などを入力し、「生成」をクリックして結果が生成されるのを待ちます。結果は`sample`フォルダに保存されます。
|
||||
|
||||
### 2. モデルのトレーニング
|
||||
完全なモデルトレーニングの流れには、データの前処理とVideo DiTのトレーニングが含まれるべきです。異なるモデルのトレーニングプロセスは類似しており、データ形式も類似しています:
|
||||
|
||||
<h4 id="data-preprocess">a. データ前処理</h4>
|
||||
|
||||
画像データを使用してLoraモデルをトレーニングする簡単なデモを提供しました。詳細は[wiki](https://github.com/aigc-apps/CogVideoX-Fun/wiki/Training-Lora)をご覧ください。
|
||||
|
||||
長いビデオのセグメンテーション、クリーニング、説明のための完全なデータ前処理リンクは、ビデオキャプションセクションの[README](cogvideox/video_caption/README.md)を参照してください。
|
||||
|
||||
テキストから画像およびビデオ生成モデルをトレーニングしたい場合。この形式でデータセットを配置する必要があります。
|
||||
|
||||
```
|
||||
📦 project/
|
||||
├── 📂 datasets/
|
||||
│ ├── 📂 internal_datasets/
|
||||
│ ├── 📂 train/
|
||||
│ │ ├── 📄 00000001.mp4
|
||||
│ │ ├── 📄 00000002.jpg
|
||||
│ │ └── 📄 .....
|
||||
│ └── 📄 json_of_internal_datasets.json
|
||||
```
|
||||
|
||||
json_of_internal_datasets.jsonは標準のJSONファイルです。json内のfile_pathは相対パスとして設定できます。以下のように:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "train/00000001.mp4",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "video"
|
||||
},
|
||||
{
|
||||
"file_path": "train/00000002.jpg",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "image"
|
||||
},
|
||||
.....
|
||||
]
|
||||
```
|
||||
|
||||
次のように絶対パスとして設定することもできます:
|
||||
```json
|
||||
[
|
||||
{
|
||||
"file_path": "/mnt/data/videos/00000001.mp4",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "video"
|
||||
},
|
||||
{
|
||||
"file_path": "/mnt/data/train/00000001.jpg",
|
||||
"text": "スーツとサングラスを着た若い男性のグループが街の通りを歩いている。",
|
||||
"type": "image"
|
||||
},
|
||||
.....
|
||||
]
|
||||
```
|
||||
|
||||
<h4 id="dit-train">b. Video DiTトレーニング </h4>
|
||||
|
||||
データ前処理時にデータ形式が相対パスの場合、```scripts/{model_name}/train.sh```を次のように設定します。
|
||||
```
|
||||
export DATASET_NAME="datasets/internal_datasets/"
|
||||
export DATASET_META_NAME="datasets/internal_datasets/json_of_internal_datasets.json"
|
||||
```
|
||||
|
||||
データ形式が絶対パスの場合、```scripts/train.sh```を次のように設定します。
|
||||
```
|
||||
export DATASET_NAME=""
|
||||
export DATASET_META_NAME="/mnt/data/json_of_internal_datasets.json"
|
||||
```
|
||||
|
||||
次に、scripts/train.shを実行します。
|
||||
```sh
|
||||
sh scripts/train.sh
|
||||
```
|
||||
いくつかのパラメータ設定の詳細について:
|
||||
Wan2.1-Funは[Readme Train](scripts/wan2.1_fun/README_TRAIN.md)と[Readme Lora](scripts/wan2.1_fun/README_TRAIN_LORA.md)を参照してください。
|
||||
Wan2.1は[Readme Train](scripts/wan2.1/README_TRAIN.md)と[Readme Lora](scripts/wan2.1/README_TRAIN_LORA.md)を参照してください。
|
||||
CogVideoX-Funは[Readme Train](scripts/cogvideox_fun/README_TRAIN.md)と[Readme Lora](scripts/cogvideox_fun/README_TRAIN_LORA.md)を参照してください。
|
||||
|
||||
# モデルの場所
|
||||
|
||||
## 1. Wan2.2-Fun
|
||||
|
||||
| 名前 | ストレージ容量 | Hugging Face | Model Scope | 説明 |
|
||||
|------|----------------|------------|-------------|------|
|
||||
| Wan2.2-Fun-A14B-InP | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-InP) | Wan2.2-Fun-14Bのテキスト・画像から動画を生成するモデルの重み。複数の解像度で学習されており、動画の最初と最後のフレームの予測をサポートしています。 |
|
||||
| Wan2.2-Fun-A14B-Control | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control) | Wan2.2-Fun-14Bの動画制御用重み。Canny、Depth、Pose、MLSDなどのさまざまな制御条件に対応しており、軌跡制御もサポートしています。512、768、1024の複数解像度での動画生成が可能で、81フレーム、16fpsで学習されています。多言語対応の予測もサポートしています。 |
|
||||
| Wan2.2-Fun-A14B-Contro-Camera | 64.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control-Camera) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control-Camera)| Wan2.2-Fun-14Bのカメラレンズ制御重み。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
| Wan2.2-VACE-Fun-A14B | 64.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.2-VACE-Fun-A14B) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.2-VACE-Fun-A14B) | VACE方式でトレーニングされたWan2.2の制御ウェイト(ベースモデルはWan2.2-T2V-A14B)。Canny、Depth、Pose、MLSD、軌道制御などの異なる制御条件をサポートします。対象を指定して動画生成が可能です。多解像度(512、768、1024)の動画予測をサポートし、81フレームで16FPSでトレーニングされています。多言語予測にも対応しています。 |
|
||||
| Wan2.2-Fun-5B-InP | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-InP) | Wan2.2-Fun-5B テキストから動画生成用の重み。121フレーム、24 FPSで学習され、先頭/末尾フレーム予測をサポート。 |
|
||||
| Wan2.2-Fun-5B-Control | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control)| Wan2.2-Fun-5B 動画制御用重み。Canny、Depth、Pose、MLSDなどの制御条件や軌道制御をサポート。121フレーム、24 FPSで学習され、多言語予測に対応。 |
|
||||
| Wan2.2-Fun-5B-Control-Camera | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control-Camera)| Wan2.2-Fun-5B カメラレンズ制御用重み。121フレーム、24 FPSで学習され、多言語予測に対応。 |
|
||||
|
||||
## 2. Wan2.2
|
||||
|
||||
| モデル名 | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|
|
||||
| Wan2.2-TI2V-5B | [🤗リンク](https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B) | [😄リンク](https://www.modelscope.cn/models/Wan-AI/Wan2.2-TI2V-5B) | 万象2.2-5B テキストから動画生成重み |
|
||||
| Wan2.2-T2V-A14B | [🤗リンク](https://huggingface.co/Wan-AI/Wan2.2-T2V-A14B) | [😄リンク](https://www.modelscope.cn/models/Wan-AI/Wan2.2-T2V-A14B) | 万象2.2-14B テキストから動画生成重み |
|
||||
| Wan2.2-I2V-A14B | [🤗リンク](https://huggingface.co/Wan-AI/Wan2.2-I2V-A14B) | [😄リンク](https://www.modelscope.cn/models/Wan-AI/Wan2.2-I2V-A14B) | 万象2.2-14B 画像から動画生成重み |
|
||||
|
||||
## 3. Wan2.1-Fun
|
||||
|
||||
V1.1:
|
||||
| 名称 | ストレージ容量 | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-V1.1-1.3B-InP | 19.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP) | Wan2.1-Fun-V1.1-1.3Bのテキスト・画像から動画生成の重み。マルチ解像度で訓練され、最初と最後の画像予測をサポートします。 |
|
||||
| Wan2.1-Fun-V1.1-14B-InP | 47.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP) | Wan2.1-Fun-V1.1-14Bのテキスト・画像から動画生成の重み。マルチ解像度で訓練され、最初と最後の画像予測をサポートします。 |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control | 19.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control)| Wan2.1-Fun-V1.1-1.3Bのビデオ制御重み。Canny、Depth、Pose、MLSDなどの異なる制御条件に対応し、参照画像+制御条件を使用した制御や軌跡制御をサポートします。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control)| Wan2.1-Fun-V1.1-14Bのビデオ制御重み。Canny、Depth、Pose、MLSDなどの異なる制御条件に対応し、参照画像+制御条件を使用した制御や軌跡制御をサポートします。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control-Camera | 19.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control-Camera) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control-Camera)| Wan2.1-Fun-V1.1-1.3Bのカメラレンズ制御重み。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
| Wan2.1-Fun-V1.1-14B-Control-Camera | 47.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control-Camera) | [😄リンク](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control-Camera)| Wan2.1-Fun-V1.1-14Bのカメラレンズ制御重み。512、768、1024のマルチ解像度での動画予測をサポートし、81フレーム、毎秒16フレームで訓練されています。多言語予測に対応しています。 |
|
||||
|
||||
|
||||
V1.0:
|
||||
| 名称 | ストレージ容量 | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-InP) | Wan2.1-Fun-1.3Bのテキスト・画像から動画生成する重み。マルチ解像度で学習され、開始・終了画像予測をサポート。 |
|
||||
| Wan2.1-Fun-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP) | Wan2.1-Fun-14Bのテキスト・画像から動画生成する重み。マルチ解像度で学習され、開始・終了画像予測をサポート。 |
|
||||
| Wan2.1-Fun-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-Control) | Wan2.1-Fun-1.3Bのビデオ制御ウェイト。Canny、Depth、Pose、MLSDなどの異なる制御条件をサポートし、トラジェクトリ制御も利用可能。512、768、1024のマルチ解像度でのビデオ予測をサポートし、81フレーム(1秒間に16フレーム)でトレーニング済みで、多言語予測にも対応しています。 |
|
||||
| Wan2.1-Fun-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-Control) | Wan2.1-Fun-14Bのビデオ制御ウェイト。Canny、Depth、Pose、MLSDなどの異なる制御条件をサポートし、トラジェクトリ制御も利用可能。512、768、1024のマルチ解像度でのビデオ予測をサポートし、81フレーム(1秒間に16フレーム)でトレーニング済みで、多言語予測にも対応しています。 |
|
||||
|
||||
## 4. Wan2.1
|
||||
|
||||
| 名称 | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|
|
||||
| Wan2.1-T2V-1.3B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-1.3B) | 万象2.1-1.3Bのテキストから動画生成する重み |
|
||||
| Wan2.1-T2V-14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-14B) | 万象2.1-14Bのテキストから動画生成する重み |
|
||||
| Wan2.1-I2V-14B-480P | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-480P) | 万象2.1-14B-480Pの画像から動画生成する重み |
|
||||
| Wan2.1-I2V-14B-720P| [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | 万象2.1-14B-720Pの画像から動画生成する重み |
|
||||
|
||||
## 5. FantasyTalking
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-I2V-14B-720P | - | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | 万象2.1-14B-720P 画像→動画モデルの重み |
|
||||
| Wav2Vec | - | [🤗Link](https://huggingface.co/facebook/wav2vec2-base-960h) | [😄Link](https://modelscope.cn/models/AI-ModelScope/wav2vec2-base-960h) | Wav2Vecモデル。Wan2.1-I2V-14B-720Pフォルダ内に配置し、`audio_encoder` という名前に変更してください |
|
||||
| FantasyTalking model | - | [🤗Link](https://huggingface.co/acvlab/FantasyTalking/) | [😄Link](https://www.modelscope.cn/models/amap_cvlab/FantasyTalking/) | 公式Audio Condition重み |
|
||||
|
||||
## 6. Qwen-Image
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image | [🤗Link](https://huggingface.co/Qwen/Qwen-Image) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image) | Qwen-Image 公式重み |
|
||||
| Qwen-Image-Edit | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit) | Qwen-Image-Edit 公式重み |
|
||||
| Qwen-Image-Edit-2509 | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit-2509) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509) | Qwen-Image-Edit-2509 公式重み |
|
||||
|
||||
## 7. Qwen-Image-Fun
|
||||
|
||||
| 名前 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image-2512-Fun-Controlnet-Union | - | [🤗リンク](https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union) | [😄リンク](https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union) | Qwen-Image-2512のControlNet重み。Canny、Depth、Pose、MLSD、Scribbleなど、複数の制御条件をサポートします。 |
|
||||
|
||||
## 8. Z-Image
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image | [🤗リンク](https://huggingface.co/Tongyi-MAI/Z-Image) | [😄リンク](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image) | Z-Imageの公式重み |
|
||||
| Z-Image-Turbo | [🤗リンク](https://huggingface.co/Tongyi-MAI/Z-Image-Turbo) | [😄リンク](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo) | Z-Image-Turboの公式重み |
|
||||
|
||||
## 9. Z-Image-Fun
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image-Fun-Controlnet-Union-2.1 | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1) | Z-ImageのControlNet重み、Canny、Depth、Pose、MLSD、ScribbleおよびGrayなど複数の制御条件に対応。 |
|
||||
| Z-Image-Fun-Lora-Distill | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill) | これはZ-Image用の蒸留LoRAで、ステップ数とCFGの両方を蒸留します。このモデルはCFGを必要とせず、推論には8ステップを使用します。 |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union | - | [🤗リンク](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union) | [😄リンク](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union) | Z-Image-Turbo用のControlNet重み。Canny、Depth、Pose、MLSDなど複数の制御条件をサポート。 |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union-2.1 | - | [🤗リンク](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | [😄リンク](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | Z-Image-TurboのControlNet重み。第1版と比較して、より多くの層に追加され、より長時間トレーニングされています。Canny、Depth、Pose、MLSDなど、複数の制御条件をサポートしています。 |
|
||||
|
||||
## 10. Flux
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| FLUX.1-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.1-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev)| FLUX.1-dev 公式重み |
|
||||
| FLUX.2-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.2-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev) | FLUX.2-dev 公式重み |
|
||||
|
||||
## 11. Flux-Fun
|
||||
|
||||
| 名前 | ストレージ | Hugging Face | ModelScope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| Flux.2-dev-Fun-Controlnet-Union | - | [🤗リンク](https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union) | [😄リンク](https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union) | Flux.2-dev 用の ControlNet 重みで、Canny、Depth、Pose、MLSD など様々な制御条件をサポートします。 |
|
||||
|
||||
## 12. HunyuanVideo
|
||||
|
||||
| 名称 | ストレージ | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| HunyuanVideo | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo) | - | HunyuanVideo-diffusers 公式重み |
|
||||
| HunyuanVideo-I2V | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo-I2V) | - | HunyuanVideo-I2V-diffusers 公式重み |
|
||||
|
||||
## 13. CogVideoX-Fun
|
||||
|
||||
V1.5:
|
||||
|
||||
| 名称 | ストレージスペース | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.5-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-5b-InP) | 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024)でビデオを予測できます。85フレーム、8フレーム/秒でトレーニングされています。 |
|
||||
| CogVideoX-Fun-V1.5-Reward-LoRAs | - | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs) | 公式の報酬逆伝播技術モデルで、CogVideoX-Fun-V1.5が生成するビデオを最適化し、人間の嗜好によりよく合うようにする。 |
|
||||
|
||||
V1.1:
|
||||
|
||||
| 名称 | ストレージスペース | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.1-2b-InP | 13.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-InP) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-InP) | 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。参照画像にノイズが追加され、V1.0と比較して動きの幅が広がっています。 |
|
||||
| CogVideoX-Fun-V1.1-5b-InP | 20.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP) | 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。参照画像にノイズが追加され、V1.0と比較して動きの幅が広がっています。 |
|
||||
| CogVideoX-Fun-V1.1-2b-Pose | 13.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Pose) | 公式のポーズコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。|
|
||||
| CogVideoX-Fun-V1.1-2b-Control | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Control) | 公式のコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。Canny、Depth、Pose、MLSDなどのさまざまなコントロール条件をサポートします。|
|
||||
| CogVideoX-Fun-V1.1-5b-Pose | 20.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Pose) | 公式のポーズコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。|
|
||||
| CogVideoX-Fun-V1.1-5b-Control | 20.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Control) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Control) | 公式のコントロールビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。Canny、Depth、Pose、MLSDなどのさまざまなコントロール条件をサポートします。|
|
||||
| CogVideoX-Fun-V1.1-Reward-LoRAs | - | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs) | 公式の報酬逆伝播技術モデルで、CogVideoX-Fun-V1.1が生成するビデオを最適化し、人間の嗜好によりよく合うようにする。 |
|
||||
|
||||
<details>
|
||||
<summary>(Obsolete) V1.0:</summary>
|
||||
|
||||
| 名称 | ストレージスペース | Hugging Face | Model Scope | 説明 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP | 13.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP) | [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-2b-InP) | 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。 |
|
||||
| CogVideoX-Fun-5b-InP | 20.0 GB | [🤗リンク](https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP)| [😄リンク](https://modelscope.cn/models/PAI/CogVideoX-Fun-5b-InP)| 公式のグラフ生成ビデオモデルは、複数の解像度(512、768、1024、1280)でビデオを予測できます。49フレーム、8フレーム/秒でトレーニングされています。|
|
||||
</details>
|
||||
|
||||
# 参考文献
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
|
||||
- Wan2.1: https://github.com/Wan-Video/Wan2.1/
|
||||
- Wan2.2: https://github.com/Wan-Video/Wan2.2/
|
||||
- Diffusers: https://github.com/huggingface/diffusers
|
||||
- Qwen-Image: https://github.com/QwenLM/Qwen-Image
|
||||
- Self-Forcing: https://github.com/guandeh17/Self-Forcing
|
||||
- Flux: https://github.com/black-forest-labs/flux
|
||||
- Flux2: https://github.com/black-forest-labs/flux2
|
||||
- HunyuanVideo: https://github.com/Tencent-Hunyuan/HunyuanVideo
|
||||
- ComfyUI-KJNodes: https://github.com/kijai/ComfyUI-KJNodes
|
||||
- ComfyUI-EasyAnimateWrapper: https://github.com/kijai/ComfyUI-EasyAnimateWrapper
|
||||
- ComfyUI-CameraCtrl-Wrapper: https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper
|
||||
- CameraCtrl: https://github.com/hehao13/CameraCtrl
|
||||
|
||||
# ライセンス
|
||||
このプロジェクトは[Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE)の下でライセンスされています。
|
||||
|
||||
CogVideoX-2Bモデル(対応するTransformersモジュール、VAEモジュールを含む)は、[Apache 2.0ライセンス](LICENSE)の下でリリースされています。
|
||||
|
||||
CogVideoX-5Bモデル(Transformersモジュール)は、[CogVideoXライセンス](https://huggingface.co/THUDM/CogVideoX-5b/blob/main/LICENSE)の下でリリースされています。
|
||||
@@ -1,45 +1,60 @@
|
||||
# CogVideoX-Fun
|
||||
# VideoX-Fun
|
||||
|
||||
😊 Welcome!
|
||||
|
||||
[English](./README.md) | 简体中文
|
||||
CogVideoX-Fun:
|
||||
[](https://huggingface.co/spaces/alibaba-pai/CogVideoX-Fun-5b)
|
||||
|
||||
Wan-Fun:
|
||||
[](https://huggingface.co/spaces/alibaba-pai/Wan2.1-Fun-1.3B-InP)
|
||||
|
||||
[English](./README.md) | 简体中文 | [日本語](./README_ja-JP.md)
|
||||
|
||||
# 目录
|
||||
- [目录](#目录)
|
||||
- [简介](#简介)
|
||||
- [快速启动](#快速启动)
|
||||
- [视频作品](#视频作品)
|
||||
- [如何使用](#如何使用)
|
||||
- [模型地址](#模型地址)
|
||||
- [未来计划](#未来计划)
|
||||
- [参考文献](#参考文献)
|
||||
- [许可证](#许可证)
|
||||
|
||||
# 简介
|
||||
CogVideoX-Fun是一个基于CogVideoX结构修改后的的pipeline,是一个生成条件更自由的CogVideoX,可用于生成AI图片与视频、训练Diffusion Transformer的基线模型与Lora模型,我们支持从已经训练好的CogVideoX-Fun模型直接进行预测,生成不同分辨率,6秒左右、fps8的视频(1 ~ 49帧),也支持用户训练自己的基线模型与Lora模型,进行一定的风格变换。
|
||||
VideoX-Fun是一个视频生成的pipeline,可用于生成AI图片与视频、训练Diffusion Transformer的基线模型与Lora模型,我们支持从已经训练好的基线模型直接进行预测,生成不同分辨率,不同秒数、不同FPS的视频,也支持用户训练自己的基线模型与Lora模型,进行一定的风格变换。
|
||||
|
||||
我们会逐渐支持从不同平台快速启动,请参阅 [快速启动](#快速启动)。
|
||||
|
||||
新特性:
|
||||
- 创建代码!现在支持 Windows 和 Linux。支持最大256x256x49到1024x1024x49的任意分辨率的视频生成。[ 2024.09.09 ]
|
||||
- 更新支持Wan2.2系列模型、Wan-VACE控制模型、支持Fantasy Talking数字人模型、Qwen-Image和Flux图片生成模型等。[2025.10.16]。
|
||||
- 更新Wan2.1-Fun-V1.1版本:支持14B与1.3B模型Control+参考图模型,支持镜头控制,另外Inpaint模型重新训练,性能更佳。[2025.04.25]
|
||||
- 更新Wan2.1-Fun-V1.0版本:支持14B与1.3B模型的I2V和Control模型,支持首尾图预测。[2025.03.26]
|
||||
- 更新CogVideoX-Fun-V1.5版本:上传I2V模型与相关训练预测代码。[2024.12.16]
|
||||
- 奖励Lora支持:通过奖励反向传播技术训练Lora,以优化生成的视频,使其更好地与人类偏好保持一致,[更多信息](scripts/README_TRAIN_REWARD.md)。新版本的控制模型,支持不同的控制条件,如Canny、Depth、Pose、MLSD等。[2024.11.21]
|
||||
- diffusers支持:CogVideoX-Fun Control现在在diffusers中得到了支持。感谢 [a-r-r-o-w](https://github.com/a-r-r-o-w)在这个 [PR](https://github.com/huggingface/diffusers/pull/9671)中贡献了支持。查看[文档](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cogvideox)以了解更多信息。[2024.10.16]
|
||||
- 更新CogVideoX-Fun-V1.1版本:重新训练i2v模型,添加Noise,使得视频的运动幅度更大。上传控制模型训练代码与Control模型。[2024.09.29]
|
||||
- 更新CogVideoX-Fun-V1.0版本:创建代码!现在支持 Windows 和 Linux。支持2b与5b最大256x256x49到1024x1024x49的任意分辨率的视频生成。[2024.09.18]
|
||||
|
||||
功能概览:
|
||||
- [数据预处理](#data-preprocess)
|
||||
- [训练DiT](#dit-train)
|
||||
- [模型生成](#video-gen)
|
||||
|
||||
这些是我们的生成结果 [GALLERY](scripts/Result_Gallery.md) (点击下方的图片可查看视频):
|
||||
|
||||
我们的ui界面如下:
|
||||

|
||||
|
||||
# 快速启动
|
||||
### 1. 云使用: AliyunDSW/Docker
|
||||
#### a. 通过阿里云 DSW
|
||||
正在路上
|
||||
DSW 有免费 GPU 时间,用户可申请一次,申请后3个月内有效。
|
||||
|
||||
阿里云在[Freetier](https://free.aliyun.com/?product=9602825&crowd=enterprise&spm=5176.28055625.J_5831864660.1.e939154aRgha4e&scm=20140722.M_9974135.P_110.MO_1806-ID_9974135-MID_9974135-CID_30683-ST_8512-V_1)提供免费GPU时间,获取并在阿里云PAI-DSW中使用,5分钟内即可启动CogVideoX-Fun。
|
||||
|
||||
[](https://gallery.pai-ml.com/#/preview/deepLearning/cv/cogvideox_fun)
|
||||
|
||||
#### b. 通过ComfyUI
|
||||
我们的ComfyUI界面如下,具体查看[ComfyUI README](comfyui/README.md)。
|
||||

|
||||

|
||||
|
||||
#### c. 通过docker
|
||||
使用docker的情况下,请保证机器中已经正确安装显卡驱动与CUDA环境,然后以此执行以下命令:
|
||||
@@ -52,25 +67,28 @@ docker pull mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cud
|
||||
docker run -it -p 7860:7860 --network host --gpus all --security-opt seccomp:unconfined --shm-size 200g mybigpai-public-registry.cn-beijing.cr.aliyuncs.com/easycv/torch_cuda:cogvideox_fun
|
||||
|
||||
# clone code
|
||||
git clone https://github.com/aigc-apps/CogVideoX-Fun.git
|
||||
git clone https://github.com/aigc-apps/VideoX-Fun.git
|
||||
|
||||
# enter CogVideoX-Fun's dir
|
||||
cd CogVideoX-Fun
|
||||
# enter VideoX-Fun's dir
|
||||
cd VideoX-Fun
|
||||
|
||||
# download weights
|
||||
mkdir models/Diffusion_Transformer
|
||||
mkdir models/Personalized_Model
|
||||
|
||||
wget https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz -O models/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz
|
||||
# Please use the hugginface link or modelscope link to download the model.
|
||||
# CogVideoX-Fun
|
||||
# https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP
|
||||
# https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP
|
||||
|
||||
cd models/Diffusion_Transformer/
|
||||
tar -xvf CogVideoX-Fun-2b-InP.tar.gz
|
||||
cd ../../
|
||||
# Wan
|
||||
# https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP
|
||||
# https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP
|
||||
```
|
||||
|
||||
### 2. 本地安装: 环境检查/下载/安装
|
||||
#### a. 环境检查
|
||||
我们已验证CogVideoX-Fun可在以下环境中执行:
|
||||
我们已验证该库可在以下环境中执行:
|
||||
|
||||
Windows 的详细信息:
|
||||
- 操作系统 Windows 10
|
||||
@@ -93,35 +111,353 @@ Linux 的详细信息:
|
||||
#### b. 权重放置
|
||||
我们最好将[权重](#model-zoo)按照指定路径进行放置:
|
||||
|
||||
**通过comfyui**:
|
||||
将模型放入Comfyui的权重文件夹`ComfyUI/models/Fun_Models/`:
|
||||
```
|
||||
📦 ComfyUI/
|
||||
├── 📂 models/
|
||||
│ └── 📂 Fun_Models/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
|
||||
│ ├── 📂 Wan2.1-Fun-V1.1-14B-InP
|
||||
│ └── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
|
||||
```
|
||||
|
||||
**运行自身的python文件或ui界面**:
|
||||
```
|
||||
📦 models/
|
||||
├── 📂 Diffusion_Transformer/
|
||||
│ └── 📂 CogVideoX-Fun-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-2b-InP/
|
||||
│ ├── 📂 CogVideoX-Fun-V1.1-5b-InP/
|
||||
│ ├── 📂 Wan2.1-Fun-V1.1-14B-InP
|
||||
│ └── 📂 Wan2.1-Fun-V1.1-1.3B-InP/
|
||||
├── 📂 Personalized_Model/
|
||||
│ └── your trained trainformer model / your trained lora model (for UI load)
|
||||
```
|
||||
|
||||
# 视频作品
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-InP && Wan2.1-Fun-V1.1-1.3B-InP
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d6a46051-8fe6-4174-be12-95ee52c96298" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8572c656-8548-4b1f-9ec8-8107c6236cb1" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3411c95-483d-4e30-bc72-483c2b288918" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/b2f5addc-06bd-49d9-b925-973090a32800" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/747b6ab8-9617-4ba2-84a0-b51c0efbd4f8" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ae94dcda-9d5e-4bae-a86f-882c4282a367" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a4aa1a82-e162-4ab5-8f05-72f79568a191" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/83c005b8-ccbc-44a0-a845-c0472763119c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control && Wan2.1-Fun-V1.1-1.3B-Control
|
||||
|
||||
Generic Control Video + Reference Image:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Reference Image
|
||||
</td>
|
||||
<td>
|
||||
Control Video
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-14B-Control
|
||||
</td>
|
||||
<td>
|
||||
Wan2.1-Fun-V1.1-1.3B-Control
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<image src="https://github.com/user-attachments/assets/221f2879-3b1b-4fbd-84f9-c3e0b0b3533e" width="100%" controls preload loop></image>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f361af34-b3b3-4be4-9d03-cd478cb3dfc5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85e2f00b-6ef0-4922-90ab-4364afb2c93d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1f3fe763-2754-4215-bc9a-ae804950d4b3" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</table>
|
||||
|
||||
|
||||
Generic Control Video (Canny, Pose, Depth, etc.) and Trajectory Control:
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/f35602c4-9f0a-4105-9762-1e3a88abbac6" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8b0f0e87-f1be-4915-bb35-2d53c852333e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/972012c1-772b-427a-bce6-ba8b39edcfad" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
</table>
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ce62d0bd-82c0-4d7b-9c49-7e0e4b605745" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/89dfbffb-c4a6-4821-bcef-8b1489a3ca00" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/72a43e33-854f-4349-861b-c959510d1a84" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bb0ce13d-dee0-4049-9eec-c92f3ebc1358" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7840c333-7bec-4582-ba63-20a39e1139c4" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/85147d30-ae09-4f36-a077-2167f7a578c0" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### Wan2.1-Fun-V1.1-14B-Control-Camera && Wan2.1-Fun-V1.1-1.3B-Control-Camera
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
Pan Up
|
||||
</td>
|
||||
<td>
|
||||
Pan Left
|
||||
</td>
|
||||
<td>
|
||||
Pan Right
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/869fe2ef-502a-484e-8656-fe9e626b9f63" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/2d4185c8-d6ec-4831-83b4-b1dbfc3616fa" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7dfb7cad-ed24-4acc-9377-832445a07ec7" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
Pan Down
|
||||
</td>
|
||||
<td>
|
||||
Pan Up + Pan Left
|
||||
</td>
|
||||
<td>
|
||||
Pan Up + Pan Right
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3ea3a08d-f2df-43a2-976e-bf2659345373" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/4a85b028-4120-4293-886b-b8afe2d01713" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ad0d58c1-13ef-450c-b658-4fed7ff5ed36" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B
|
||||
|
||||
Resolution-1024
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/34e7ec8f-293e-4655-bb14-5e1ee476f788" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7809c64f-eb8c-48a9-8bdc-ca9261fd5434" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/8e76aaa4-c602-44ac-bcb4-8b24b72c386c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/19dba894-7c35-4f25-b15c-384167ab3b03" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
|
||||
Resolution-768
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/0bc339b9-455b-44fd-8917-80272d702737" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/70a043b9-6721-4bd9-be47-78b7ec5c27e9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d5dd6c09-14f3-40f8-8b6d-91e26519b8ac" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/9327e8bc-4f17-46b0-b50d-38c250a9483a" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
Resolution-512
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ef407030-8062-454d-aba3-131c21e6b58c" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/7610f49e-38b6-4214-aa48-723ae4d1b07e" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/1fff0567-1e15-415c-941e-53ee8ae2c841" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/bcec48da-b91b-43a0-9d50-cf026e00fa4f" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
### CogVideoX-Fun-V1.1-5B-Control
|
||||
|
||||
<table border="0" style="width: 100%; text-align: left; margin-top: 20px;">
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/53002ce2-dd18-4d4f-8135-b6f68364cabd" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/a1a07cf8-d86d-4cd2-831f-18a6c1ceee1d" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/3224804f-342d-4947-918d-d9fec8e3d273" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<tr>
|
||||
<td>
|
||||
A young woman with beautiful clear eyes and blonde hair, wearing white clothes and twisting her body, with the camera focused on her face. High quality, masterpiece, best quality, high resolution, ultra-fine, dreamlike.
|
||||
</td>
|
||||
<td>
|
||||
A young woman with beautiful clear eyes and blonde hair, wearing white clothes and twisting her body, with the camera focused on her face. High quality, masterpiece, best quality, high resolution, ultra-fine, dreamlike.
|
||||
</td>
|
||||
<td>
|
||||
A young bear.
|
||||
</td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ea908454-684b-4d60-b562-3db229a250a9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/ffb7c6fc-8b69-453b-8aad-70dfae3899b9" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
<td>
|
||||
<video src="https://github.com/user-attachments/assets/d3f757a3-3551-4dcb-9372-7a61469813f5" width="100%" controls preload loop></video>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
# 如何使用
|
||||
|
||||
<h3 id="video-gen">1. 生成 </h3>
|
||||
|
||||
#### a. 视频生成
|
||||
##### i、运行python文件
|
||||
- 步骤1:下载对应[权重](#model-zoo)放入models文件夹。
|
||||
- 步骤2:在predict_t2v.py文件中修改prompt、neg_prompt、guidance_scale和seed。
|
||||
- 步骤3:运行predict_t2v.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos-t2v文件夹中。
|
||||
- 步骤4:如果想结合自己训练的其他backbone与Lora,则看情况修改predict_t2v.py中的predict_t2v.py和lora_path。
|
||||
#### a、显存节省方案
|
||||
由于Wan2.1的参数非常大,我们需要考虑显存节省方案,以节省显存适应消费级显卡。我们给每个预测文件都提供了GPU_memory_mode,可以在model_cpu_offload,model_cpu_offload_and_qfloat8,sequential_cpu_offload中进行选择。该方案同样适用于CogVideoX-Fun的生成。
|
||||
|
||||
##### ii、通过ui界面
|
||||
- 步骤1:下载对应[权重](#model-zoo)放入models文件夹。
|
||||
- 步骤2:运行app.py文件,进入gradio页面。
|
||||
- 步骤3:根据页面选择生成模型,填入prompt、neg_prompt、guidance_scale和seed等,点击生成,等待生成结果,结果保存在sample文件夹中。
|
||||
- model_cpu_offload代表整个模型在使用后会进入cpu,可以节省部分显存。
|
||||
- model_cpu_offload_and_qfloat8代表整个模型在使用后会进入cpu,并且对transformer模型进行了float8的量化,可以节省更多的显存。
|
||||
- sequential_cpu_offload代表模型的每一层在使用后会进入cpu,速度较慢,节省大量显存。
|
||||
|
||||
##### iii、通过comfyui
|
||||
qfloat8会部分降低模型的性能,但可以节省更多的显存。如果显存足够,推荐使用model_cpu_offload。
|
||||
|
||||
#### b、通过comfyui
|
||||
具体查看[ComfyUI README](comfyui/README.md)。
|
||||
|
||||
#### c、运行python文件
|
||||
|
||||
##### i、单卡运行:
|
||||
|
||||
- 步骤1:下载对应[权重](#model-zoo)放入models文件夹。
|
||||
- 步骤2:根据不同的权重与预测目标使用不同的文件进行预测。当前该库支持CogVideoX-Fun、Wan2.1和Wan2.1-Fun,在examples文件夹下用文件夹名以区分,不同模型支持的功能不同,请视具体情况予以区分。以CogVideoX-Fun为例。
|
||||
- 文生视频:
|
||||
- 使用examples/cogvideox_fun/predict_t2v.py文件中修改prompt、neg_prompt、guidance_scale和seed。
|
||||
- 而后运行examples/cogvideox_fun/predict_t2v.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos文件夹中。
|
||||
- 图生视频:
|
||||
- 使用examples/cogvideox_fun/predict_i2v.py文件中修改validation_image_start、validation_image_end、prompt、neg_prompt、guidance_scale和seed。
|
||||
- validation_image_start是视频的开始图片,validation_image_end是视频的结尾图片。
|
||||
- 而后运行examples/cogvideox_fun/predict_i2v.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos_i2v文件夹中。
|
||||
- 视频生视频:
|
||||
- 使用examples/cogvideox_fun/predict_v2v.py文件中修改validation_video、validation_image_end、prompt、neg_prompt、guidance_scale和seed。
|
||||
- validation_video是视频生视频的参考视频。您可以使用以下视频运行演示:[演示视频](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/play_guitar.mp4)
|
||||
- 而后运行examples/cogvideox_fun/predict_v2v.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos_v2v文件夹中。
|
||||
- 普通控制生视频(Canny、Pose、Depth等):
|
||||
- 使用examples/cogvideox_fun/predict_v2v_control.py文件中修改control_video、validation_image_end、prompt、neg_prompt、guidance_scale和seed。
|
||||
- control_video是控制生视频的控制视频,是使用Canny、Pose、Depth等算子提取后的视频。您可以使用以下视频运行演示:[演示视频](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1.1/pose.mp4)
|
||||
- 而后运行examples/cogvideox_fun/predict_v2v_control.py文件,等待生成结果,结果保存在samples/cogvideox-fun-videos_v2v_control文件夹中。
|
||||
- 步骤3:如果想结合自己训练的其他backbone与Lora,则看情况修改examples/{model_name}/predict_t2v.py中的examples/{model_name}/predict_i2v.py和lora_path。
|
||||
|
||||
##### ii、多卡运行:
|
||||
在使用多卡预测时请注意安装xfuser仓库,推荐安装xfuser==0.4.2和yunchang==0.6.2。
|
||||
```
|
||||
pip install xfuser==0.4.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
pip install yunchang==0.6.2 --progress-bar off -i https://mirrors.aliyun.com/pypi/simple/
|
||||
```
|
||||
|
||||
请确保ulysses_degree和ring_degree的乘积等于使用的GPU数量。例如,如果您使用8个GPU,则可以设置ulysses_degree=2和ring_degree=4,也可以设置ulysses_degree=4和ring_degree=2。
|
||||
|
||||
ulysses_degree是在head进行切分后并行生成,ring_degree是在sequence上进行切分后并行生成。ring_degree相比ulysses_degree有更大的通信成本,在设置参数时需要结合序列长度和模型的head数进行设置。
|
||||
|
||||
以8卡并行预测为例。
|
||||
- 以Wan2.1-Fun-V1.1-14B-InP为例,其head数为40,ulysses_degree需要设置为其可以整除的数如2、4、8等。因此在使用8卡并行预测时,可以设置ulysses_degree=8和ring_degree=1.
|
||||
- 以Wan2.1-Fun-V1.1-1.3B-InP为例,其head数为12,ulysses_degree需要设置为其可以整除的数如2、4等。因此在使用8卡并行预测时,可以设置ulysses_degree=4和ring_degree=2.
|
||||
|
||||
设置完成后,使用如下指令进行并行预测:
|
||||
```sh
|
||||
torchrun --nproc-per-node=8 examples/wan2.1_fun/predict_t2v.py
|
||||
```
|
||||
|
||||
#### d、通过ui界面
|
||||
|
||||
webui支持文生视频、图生视频、视频生视频和普通控制生视频(Canny、Pose、Depth等)。当前该库支持CogVideoX-Fun、Wan2.1和Wan2.1-Fun,在examples文件夹下用文件夹名以区分,不同模型支持的功能不同,请视具体情况予以区分。以CogVideoX-Fun为例。
|
||||
|
||||
- 步骤1:下载对应[权重](#model-zoo)放入models文件夹。
|
||||
- 步骤2:运行examples/cogvideox_fun/app.py文件,进入gradio页面。
|
||||
- 步骤3:根据页面选择生成模型,填入prompt、neg_prompt、guidance_scale和seed等,点击生成,等待生成结果,结果保存在sample文件夹中。
|
||||
|
||||
### 2. 模型训练
|
||||
一个完整的CogVideoX-Fun训练链路应该包括数据预处理和Video DiT训练。
|
||||
一个完整的模型训练链路应该包括数据预处理和Video DiT训练。不同模型的训练流程类似,数据格式也类似:
|
||||
|
||||
<h4 id="data-preprocess">a.数据预处理</h4>
|
||||
我们给出了一个简单的demo通过图片数据训练lora模型,详情可以查看[wiki](https://github.com/aigc-apps/CogVideoX-Fun/wiki/Training-Lora)。
|
||||
@@ -175,14 +511,10 @@ json_of_internal_datasets.json是一个标准的json文件。json中的file_path
|
||||
```
|
||||
<h4 id="dit-train">b. Video DiT训练 </h4>
|
||||
|
||||
如果数据预处理时,数据的格式为相对路径,则进入scripts/train.sh进行如下设置。
|
||||
如果数据预处理时,数据的格式为相对路径,则进入scripts/{model_name}/train.sh进行如下设置。
|
||||
```
|
||||
export DATASET_NAME="datasets/internal_datasets/"
|
||||
export DATASET_META_NAME="datasets/internal_datasets/json_of_internal_datasets.json"
|
||||
|
||||
...
|
||||
|
||||
train_data_format="normal"
|
||||
```
|
||||
|
||||
如果数据的格式为绝对路径,则进入scripts/train.sh进行如下设置。
|
||||
@@ -196,21 +528,170 @@ export DATASET_META_NAME="/mnt/data/json_of_internal_datasets.json"
|
||||
sh scripts/train.sh
|
||||
```
|
||||
|
||||
关于一些参数的设置细节,可以查看[Readme Train](scripts/README_TRAIN.md)与[Readme Lora](scripts/README_TRAIN_LORA.md)
|
||||
关于一些参数的设置细节:
|
||||
Wan2.1-Fun可以查看[Readme Train](scripts/wan2.1_fun/README_TRAIN.md)与[Readme Lora](scripts/wan2.1_fun/README_TRAIN_LORA.md)。
|
||||
Wan2.1可以查看[Readme Train](scripts/wan2.1/README_TRAIN.md)与[Readme Lora](scripts/wan2.1/README_TRAIN_LORA.md)。
|
||||
CogVideoX-Fun可以查看[Readme Train](scripts/cogvideox_fun/README_TRAIN.md)与[Readme Lora](scripts/cogvideox_fun/README_TRAIN_LORA.md)。
|
||||
|
||||
|
||||
# 模型地址
|
||||
| 名称 | 存储空间 | 下载地址 | Hugging Face | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP.tar.gz | 解压前 9.69 GB / 解压后 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP)| 官方的图生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以144帧、每秒24帧进行训练 |
|
||||
## 1.Wan2.2-Fun
|
||||
|
||||
# 未来计划
|
||||
- 支持CogVideoX-5b。
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.2-Fun-A14B-InP | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-InP) | Wan2.2-Fun-14B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.2-Fun-A14B-Control | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control)| Wan2.2-Fun-14B视频控制权重,支持不同的控制条件,如Canny、Depth、Pose、MLSD等,同时支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.2-Fun-A14B-Control-Camera | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-A14B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-A14B-Control-Camera)| Wan2.2-Fun-14B相机镜头控制权重。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.2-VACE-Fun-A14B | 64.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-VACE-Fun-A14B) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-VACE-Fun-A14B)| 以VACE方案训练的Wan2.2控制权重,基础模型为Wan2.2-T2V-A14B,支持不同的控制条件,如Canny、Depth、Pose、MLSD、轨迹控制等。支持通过主体指定生视频。支持多分辨率(512,768,1024)的视频预测,支持多分辨率(512,768,1024)的视频预测,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.2-Fun-5B-InP | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-InP) | Wan2.2-Fun-5B文图生视频权重,以121帧、每秒24帧进行训练支持首尾图预测。 |
|
||||
| Wan2.2-Fun-5B-Control | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control)| Wan2.2-Fun-5B视频控制权重,支持不同的控制条件,如Canny、Depth、Pose、MLSD等,同时支持使用轨迹控制。以121帧、每秒24帧进行训练,支持多语言预测 |
|
||||
| Wan2.2-Fun-5B-Control-Camera | 23.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.2-Fun-5B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.2-Fun-5B-Control-Camera)| Wan2.2-Fun-5B相机镜头控制权重。以121帧、每秒24帧进行训练,支持多语言预测 |
|
||||
|
||||
## 2. Wan2.2
|
||||
|
||||
| 名称 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|
|
||||
| Wan2.2-TI2V-5B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-TI2V-5B) | 万象2.2-5B文生视频权重 |
|
||||
| Wan2.2-T2V-A14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-T2V-A14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-T2V-A14B) | 万象2.2-14B文生视频权重 |
|
||||
| Wan2.2-I2V-A14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.2-I2V-A14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.2-I2V-A14B) | 万象2.2-14B图生视频权重 |
|
||||
|
||||
## 3. Wan2.1-Fun
|
||||
|
||||
V1.1:
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-V1.1-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-InP) | Wan2.1-Fun-V1.1-1.3B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.1-Fun-V1.1-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-InP) | Wan2.1-Fun-V1.1-14B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control)| Wan2.1-Fun-V1.1-1.3B视频控制权重支持不同的控制条件,如Canny、Depth、Pose、MLSD等,支持参考图 + 控制条件进行控制,支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.1-Fun-V1.1-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control)| Wan2.1-Fun-V1.1-14B视视频控制权重支持不同的控制条件,如Canny、Depth、Pose、MLSD等,支持参考图 + 控制条件进行控制,支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.1-Fun-V1.1-1.3B-Control-Camera | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-1.3B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-1.3B-Control-Camera)| Wan2.1-Fun-V1.1-1.3B相机镜头控制权重。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.1-Fun-V1.1-14B-Control-Camera | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-V1.1-14B-Control-Camera) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-V1.1-14B-Control-Camera)| Wan2.1-Fun-V1.1-14B相机镜头控制权重。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
|
||||
V1.0:
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-Fun-1.3B-InP | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-InP) | Wan2.1-Fun-1.3B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.1-Fun-14B-InP | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-InP) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-InP) | Wan2.1-Fun-14B文图生视频权重,以多分辨率训练,支持首尾图预测。 |
|
||||
| Wan2.1-Fun-1.3B-Control | 19.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-1.3B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-1.3B-Control)| Wan2.1-Fun-1.3B视频控制权重,支持不同的控制条件,如Canny、Depth、Pose、MLSD等,同时支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
| Wan2.1-Fun-14B-Control | 47.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/Wan2.1-Fun-14B-Control) | [😄Link](https://modelscope.cn/models/PAI/Wan2.1-Fun-14B-Control)| Wan2.1-Fun-14B视频控制权重,支持不同的控制条件,如Canny、Depth、Pose、MLSD等,同时支持使用轨迹控制。支持多分辨率(512,768,1024)的视频预测,,以81帧、每秒16帧进行训练,支持多语言预测 |
|
||||
|
||||
## 4. Wan2.1
|
||||
|
||||
| 名称 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|
|
||||
| Wan2.1-T2V-1.3B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-1.3B) | 万象2.1-1.3B文生视频权重 |
|
||||
| Wan2.1-T2V-14B | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-T2V-14B) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-T2V-14B) | 万象2.1-14B文生视频权重 |
|
||||
| Wan2.1-I2V-14B-480P | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-480P) | 万象2.1-14B-480P图生视频权重 |
|
||||
| Wan2.1-I2V-14B-720P| [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | 万象2.1-14B-720P图生视频权重 |
|
||||
|
||||
## 5. FantasyTalking
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Wan2.1-I2V-14B-720P | - | [🤗Link](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P) | [😄Link](https://www.modelscope.cn/models/Wan-AI/Wan2.1-I2V-14B-720P) | 万象2.1-14B-720P图生视频权重 |
|
||||
| Wav2Vec | - | [🤗Link](https://huggingface.co/facebook/wav2vec2-base-960h) | [😄Link](https://modelscope.cn/models/AI-ModelScope/wav2vec2-base-960h) | Wav2Vec模型,请放在Wan2.1-I2V-14B-720P文件夹下,命名为audio_encoder |
|
||||
| FantasyTalking model | - | [🤗Link](https://huggingface.co/acvlab/FantasyTalking/) | [😄Link](https://www.modelscope.cn/models/amap_cvlab/FantasyTalking/) | 官方Audio Condition的权重。 |
|
||||
|
||||
## 6. Qwen-Image
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image | [🤗Link](https://huggingface.co/Qwen/Qwen-Image) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image) | Qwen-Image官方权重 |
|
||||
| Qwen-Image-Edit | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit) | Qwen-Image-Edit官方权重 |
|
||||
| Qwen-Image-Edit-2509 | [🤗Link](https://huggingface.co/Qwen/Qwen-Image-Edit-2509) | [😄Link](https://modelscope.cn/models/Qwen/Qwen-Image-Edit-2509) | Qwen-Image-Edit-2509官方权重 |
|
||||
|
||||
## 7. Qwen-Image-Fun
|
||||
|
||||
| 名称 | 存储 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Qwen-Image-2512-Fun-Controlnet-Union | - | [🤗链接](https://huggingface.co/alibaba-pai/Qwen-Image-2512-Fun-Controlnet-Union) | [😄链接](https://modelscope.cn/models/PAI/Qwen-Image-2512-Fun-Controlnet-Union) | Qwen-Image-2512的ControlNet权重,支持多种控制条件,如Canny、Depth、Pose、MLSD、Scribble等。 |
|
||||
|
||||
## 8. Z-Image
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image | [🤗Link](https://huggingface.co/Tongyi-MAI/Z-Image) | [😄Link](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image) | Z-Image官方权重 |
|
||||
| Z-Image-Turbo | [🤗Link](https://huggingface.co/Tongyi-MAI/Z-Image-Turbo) | [😄Link](https://www.modelscope.cn/models/Tongyi-MAI/Z-Image-Turbo) | Z-Image-Turbo官方权重 |
|
||||
|
||||
## 9. Z-Image-Fun
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Z-Image-Fun-Controlnet-Union-2.1 | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Controlnet-Union-2.1) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Controlnet-Union-2.1) | Z-Image 的 ControlNet 权重,支持 Canny、Depth、Pose、MLSD、Scribble和Gray 等多种控制条件。 |
|
||||
| Z-Image-Fun-Lora-Distill | - | [🤗Link](https://huggingface.co/alibaba-pai/Z-Image-Fun-Lora-Distill) | [😄Link](https://modelscope.cn/models/PAI/Z-Image-Fun-Lora-Distill) | 这是Z-Image的蒸馏LoRA,同时蒸馏了步数和CFG。该模型不需要CFG,推理仅使用8步。 |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union | - | [🤗链接](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union) | [😄链接](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union) | Z-Image-Turbo 的 ControlNet 权重,支持 Canny、Depth、Pose、MLSD 等多种控制条件。 |
|
||||
| Z-Image-Turbo-Fun-Controlnet-Union-2.1 | - | [🤗链接](https://huggingface.co/alibaba-pai/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | [😄链接](https://modelscope.cn/models/PAI/Z-Image-Turbo-Fun-Controlnet-Union-2.1) | Z-Image-Turbo 的 ControlNet 权重,相比第一版在更多层进行添加,也训练了更长时间,支持 Canny、Depth、Pose、MLSD 等多种控制条件。 |
|
||||
|
||||
## 10. Flux
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| FLUX.1-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.1-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.1-dev) | FLUX.1-dev官方权重 |
|
||||
| FLUX.2-dev | [🤗Link](https://huggingface.co/black-forest-labs/FLUX.2-dev) | [😄Link](https://www.modelscope.cn/models/black-forest-labs/FLUX.2-dev) | FLUX.2-dev官方权重 |
|
||||
|
||||
## 11. Flux-Fun
|
||||
|
||||
| 名称 | 存储 | Hugging Face | 魔搭社区(ModelScope) | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| Flux.2-dev-Fun-Controlnet-Union | - | [🤗链接](https://huggingface.co/alibaba-pai/FLUX.2-dev-Fun-Controlnet-Union) | [😄链接](https://modelscope.cn/models/PAI/FLUX.2-dev-Fun-Controlnet-Union) | Flux.2-dev 的 ControlNet 权重,支持 Canny、Depth、Pose、MLSD 等多种控制条件。 |
|
||||
|
||||
## 12. HunyuanVideo
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| HunyuanVideo | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo) | - | HunyuanVideo-diffusers权重 |
|
||||
| HunyuanVideo-I2V | [🤗Link](https://huggingface.co/hunyuanvideo-community/HunyuanVideo-I2V) | - | HunyuanVideo-I2V-diffusers权重 |
|
||||
|
||||
## 13. CogVideoX-Fun
|
||||
|
||||
V1.5:
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.5-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.5-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-5b-InP) | 官方的图生视频权重。支持多分辨率(512,768,1024)的视频预测,以85帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.5-Reward-LoRAs | - | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.5-Reward-LoRAs) | 官方的奖励反向传播技术模型,优化CogVideoX-Fun-V1.5生成的视频,使其更好地符合人类偏好。 |
|
||||
|
||||
|
||||
V1.1:
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-V1.1-2b-InP | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-InP) | 官方的图生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.1-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-InP) | 官方的图生视频权重。添加了Noise,运动幅度相比于V1.0更大。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.1-2b-Pose | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Pose) | 官方的姿态控制生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.1-2b-Control | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-2b-Control) | 官方的控制生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练。支持不同的控制条件,如Canny、Depth、Pose、MLSD等 |
|
||||
| CogVideoX-Fun-V1.1-5b-Pose | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Pose) | 官方的姿态控制生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-V1.1-5b-Control | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Control) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-5b-Control) | 官方的控制生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练。支持不同的控制条件,如Canny、Depth、Pose、MLSD等 |
|
||||
| CogVideoX-Fun-V1.1-Reward-LoRAs | - | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-Reward-LoRAs) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-V1.1-Reward-LoRAs) | 官方的奖励反向传播技术模型,优化CogVideoX-Fun-V1.1生成的视频,使其更好地符合人类偏好。 |
|
||||
|
||||
<details>
|
||||
<summary>(Obsolete) V1.0:</summary>
|
||||
|
||||
| 名称 | 存储空间 | Hugging Face | Model Scope | 描述 |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP | 13.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-2b-InP) | 官方的图生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
| CogVideoX-Fun-5b-InP | 20.0 GB | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-5b-InP) | [😄Link](https://modelscope.cn/models/PAI/CogVideoX-Fun-5b-InP) | 官方的图生视频权重。支持多分辨率(512,768,1024,1280)的视频预测,以49帧、每秒8帧进行训练 |
|
||||
</details>
|
||||
|
||||
# 参考文献
|
||||
- CogVideo: https://github.com/THUDM/CogVideo/
|
||||
- EasyAnimate: https://github.com/aigc-apps/EasyAnimate
|
||||
- Wan2.1: https://github.com/Wan-Video/Wan2.1/
|
||||
- Wan2.2: https://github.com/Wan-Video/Wan2.2/
|
||||
- Diffusers: https://github.com/huggingface/diffusers
|
||||
- Qwen-Image: https://github.com/QwenLM/Qwen-Image
|
||||
- Self-Forcing: https://github.com/guandeh17/Self-Forcing
|
||||
- Flux: https://github.com/black-forest-labs/flux
|
||||
- Flux2: https://github.com/black-forest-labs/flux2
|
||||
- HunyuanVideo: https://github.com/Tencent-Hunyuan/HunyuanVideo
|
||||
- ComfyUI-KJNodes: https://github.com/kijai/ComfyUI-KJNodes
|
||||
- ComfyUI-EasyAnimateWrapper: https://github.com/kijai/ComfyUI-EasyAnimateWrapper
|
||||
- ComfyUI-CameraCtrl-Wrapper: https://github.com/chaojie/ComfyUI-CameraCtrl-Wrapper
|
||||
- CameraCtrl: https://github.com/hehao13/CameraCtrl
|
||||
|
||||
# 许可证
|
||||
本项目采用 [Apache License (Version 2.0)](https://github.com/modelscope/modelscope/blob/master/LICENSE).
|
||||
|
||||
CogVideoX-2B 模型 (包括其对应的Transformers模块,VAE模块) 根据 [Apache 2.0 协议](LICENSE) 许可证发布。
|
||||
CogVideoX-2B 模型 (包括其对应的Transformers模块,VAE模块) 根据 [Apache 2.0 协议](LICENSE) 许可证发布。
|
||||
|
||||
CogVideoX-5B 模型(Transformer 模块)在[CogVideoX许可证](https://huggingface.co/THUDM/CogVideoX-5b/blob/main/LICENSE)下发布.
|
||||
|
||||
@@ -1,46 +0,0 @@
|
||||
import time
|
||||
import torch
|
||||
|
||||
from cogvideox.api.api import infer_forward_api, update_diffusion_transformer_api, update_edition_api
|
||||
from cogvideox.ui.ui import ui_modelscope, ui_eas, ui
|
||||
|
||||
if __name__ == "__main__":
|
||||
# Choose the ui mode
|
||||
ui_mode = "normal"
|
||||
|
||||
# Low gpu memory mode, this is used when the GPU memory is under 16GB
|
||||
low_gpu_memory_mode = False
|
||||
# Use torch.float16 if GPU does not support torch.bfloat16
|
||||
# ome graphics cards, such as v100, 2080ti, do not support torch.bfloat16
|
||||
weight_dtype = torch.bfloat16
|
||||
|
||||
# Server ip
|
||||
server_name = "0.0.0.0"
|
||||
server_port = 7860
|
||||
|
||||
# Params below is used when ui_mode = "modelscope"
|
||||
model_name = "models/Diffusion_Transformer/CogVideoX-Fun-2b-InP"
|
||||
savedir_sample = "samples"
|
||||
|
||||
if ui_mode == "modelscope":
|
||||
demo, controller = ui_modelscope(model_name, savedir_sample, low_gpu_memory_mode, weight_dtype)
|
||||
elif ui_mode == "eas":
|
||||
demo, controller = ui_eas(model_name, savedir_sample)
|
||||
else:
|
||||
demo, controller = ui(low_gpu_memory_mode, weight_dtype)
|
||||
|
||||
# launch gradio
|
||||
app, _, _ = demo.queue(status_update_rate=1).launch(
|
||||
server_name=server_name,
|
||||
server_port=server_port,
|
||||
prevent_thread_lock=True
|
||||
)
|
||||
|
||||
# launch api
|
||||
infer_forward_api(None, app, controller)
|
||||
update_diffusion_transformer_api(None, app, controller)
|
||||
update_edition_api(None, app, controller)
|
||||
|
||||
# not close the python
|
||||
while True:
|
||||
time.sleep(5)
|
||||

|
After Width: | Height: | Size: 128 KiB |

|
After Width: | Height: | Size: 477 KiB |

|
After Width: | Height: | Size: 569 KiB |
@@ -0,0 +1,82 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9999164298554373 -0.012928004685808521 0.0 0.0 0.012928004685808521 0.9999164298554373 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9996657333896874 -0.025853848581176044 0.0 0.0 0.025853848581176044 0.9996657333896874 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.99924795250423 -0.03877537125681671 0.0 0.0 0.03877537125681671 0.99924795250423 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9986631570270832 -0.051690413005694553 0.0 0.0 0.051690413005694553 0.9986631570270832 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.997911444701132 -0.06459681520399763 0.0 0.0 0.06459681520399763 0.997911444701132 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.996992941167792 -0.07749242067193093 0.0 0.0 0.07749242067193093 0.996992941167792 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9959077999460093 -0.0903750740342681 0.0 0.0 0.0903750740342681 0.9959077999460093 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9946562024066015 -0.10324262208060146 0.0 0.0 0.10324262208060146 0.9946562024066015 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.993238357741943 -0.11609291412523022 0.0 0.0 0.11609291412523022 0.993238357741943 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9916545029310012 -0.12892380236662665 0.0 0.0 0.12892380236662665 0.9916545029310012 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.989904902699727 -0.14173314224642042 0.0 0.0 0.14173314224642042 0.989904902699727 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.987989849476809 -0.15451879280784048 0.0 0.0 0.15451879280784048 0.987989849476809 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9859096633447965 -0.16727861705355532 0.0 0.0 0.16727861705355532 0.9859096633447965 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9836646919866011 -0.18001048230285133 0.0 0.0 0.18001048230285133 0.9836646919866011 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9812553106273847 -0.19271226054808965 0.0 0.0 0.19271226054808965 0.9812553106273847 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9786819219718442 -0.20538182881038197 0.0 0.0 0.20538182881038197 0.9786819219718442 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9759449561369036 -0.21801706949442584 0.0 0.0 0.21801706949442584 0.9759449561369036 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9730448705798238 -0.23061587074244014 0.0 0.0 0.23061587074244014 0.9730448705798238 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9699821500217435 -0.24317612678714165 0.0 0.0 0.24317612678714165 0.9699821500217435 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.966757306366662 -0.25569573830370357 0.0 0.0 0.25569573830370357 0.966757306366662 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9633708786158803 -0.26817261276063736 0.0 0.0 0.26817261276063736 0.9633708786158803 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9598234327779119 -0.2806046647695387 0.0 0.0 0.2806046647695387 0.9598234327779119 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9561155617738797 -0.29298981643364064 0.0 0.0 0.29298981643364064 0.9561155617738797 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9522478853384153 -0.3053259976951131 0.0 0.0 0.3053259976951131 0.9522478853384153 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9482210499160765 -0.3176111466810532 0.0 0.0 0.3176111466810532 0.9482210499160765 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9440357285533 -0.3298432100481077 0.0 0.0 0.3298432100481077 0.9440357285533 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9396926207859084 -0.34202014332566866 0.0 0.0 0.34202014332566866 0.9396926207859084 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9351924525221897 -0.35413991125758754 0.0 0.0 0.35413991125758754 0.9351924525221897 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9305359759215686 -0.36620048814234796 0.0 0.0 0.36620048814234796 0.9305359759215686 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9257239692688904 -0.3781998581716424 0.0 0.0 0.3781998581716424 0.9257239692688904 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9207572368443384 -0.3901360157672949 0.0 0.0 0.3901360157672949 0.9207572368443384 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9156366087890059 -0.40200696591647384 0.0 0.0 0.40200696591647384 0.9156366087890059 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9103629409661467 -0.4138107245051391 0.0 0.0 0.4138107245051391 0.9103629409661467 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9049371148181253 -0.4255453186496674 0.0 0.0 0.4255453186496674 0.9049371148181253 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8993600372190931 -0.4372087870266006 0.0 0.0 0.4372087870266006 0.8993600372190931 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8936326403234123 -0.4487991802004621 0.0 0.0 0.4487991802004621 0.8936326403234123 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.887755881409856 -0.4603145609495856 0.0 0.0 0.4603145609495856 0.887755881409856 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.881730742721608 -0.4717530045899035 0.0 0.0 0.4717530045899035 0.881730742721608 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8755582313020909 -0.4831125992966384 0.0 0.0 0.4831125992966384 0.8755582313020909 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8692393788266478 -0.4943914464238468 0.0 0.0 0.4943914464238468 0.8692393788266478 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8627752414301085 -0.5055876608217589 0.0 0.0 0.5055876608217589 0.8627752414301085 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8561668995302665 -0.5166993711518628 0.0 0.0 0.5166993711518628 0.8561668995302665 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8494154576472973 -0.5277247201996818 0.0 0.0 0.5277247201996818 0.8494154576472973 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8425220442191496 -0.5386618651851877 0.0 0.0 0.5386618651851877 0.8425220442191496 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8354878114129365 -0.549508978070806 0.0 0.0 0.549508978070806 0.8354878114129365 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.828313934932363 -0.5602642458669524 0.0 0.0 0.5602642458669524 0.828313934932363 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8210016138212185 -0.5709258709350582 0.0 0.0 0.5709258709350582 0.8210016138212185 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8135520702629676 -0.5814920712880266 0.0 0.0 0.5814920712880266 0.8135520702629676 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8059665493764744 -0.5919610808880759 0.0 0.0 0.5919610808880759 0.8059665493764744 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.798246319007893 -0.6023311499419145 0.0 0.0 0.6023311499419145 0.798246319007893 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7903926695187593 -0.6126005451932028 0.0 0.0 0.6126005451932028 0.7903926695187593 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7824069135703198 -0.622767550212249 0.0 0.0 0.622767550212249 0.7824069135703198 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7742903859041323 -0.632830465682895 0.0 0.0 0.632830465682895 0.7742903859041323 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7660444431189781 -0.6427876096865393 0.0 0.0 0.6427876096865393 0.7660444431189781 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7576704634441179 -0.6526373179832544 0.0 0.0 0.6526373179832544 0.7576704634441179 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.749169846508936 -0.6623779442899478 0.0 0.0 0.6623779442899478 0.749169846508936 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7405440131090046 -0.6720078605555224 0.0 0.0 0.6720078605555224 0.7405440131090046 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7317944049686121 -0.6815254572329892 0.0 0.0 0.6815254572329892 0.7317944049686121 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7229224844997929 -0.6909291435484877 0.0 0.0 0.6909291435484877 0.7229224844997929 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7139297345578991 -0.7002173477671684 0.0 0.0 0.7002173477671684 0.7139297345578991 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7048176581937561 -0.7093885174558928 0.0 0.0 0.7093885174558928 0.7048176581937561 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.695587778402442 -0.7184411197427074 0.0 0.0 0.7184411197427074 0.695587778402442 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6862416378687336 -0.7273736415730486 0.0 0.0 0.7273736415730486 0.6862416378687336 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6767807987092621 -0.7361845899626351 0.0 0.0 0.7361845899626351 0.6767807987092621 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6672068422114197 -0.7448724922470058 0.0 0.0 0.7448724922470058 0.6672068422114197 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6575213685690637 -0.7534358963276606 0.0 0.0 0.7534358963276606 0.6575213685690637 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.647725996615059 -0.761873370914766 0.0 0.0 0.761873370914766 0.647725996615059 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6378223635507061 -0.7701835057663796 0.0 0.0 0.7701835057663796 0.6378223635507061 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6278121246720987 -0.7783649119241599 0.0 0.0 0.7783649119241599 0.6278121246720987 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6176969530934572 -0.7864162219455162 0.0 0.0 0.7864162219455162 0.6176969530934572 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6074785394674836 -0.7943360901321637 0.0 0.0 0.7943360901321637 0.6074785394674836 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5971585917027863 -0.8021231927550437 0.0 0.0 0.8021231927550437 0.5971585917027863 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5867388346784178 -0.8097762282755726 0.0 0.0 0.8097762282755726 0.5867388346784178 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5762210099555805 -0.8172939175631805 0.0 0.0 0.8172939175631805 0.5762210099555805 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5656068754865388 -0.8246750041091067 0.0 0.0 0.8246750041091067 0.5656068754865388 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.554898205320797 -0.8319182542364115 0.0 0.0 0.8319182542364115 0.554898205320797 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5440967893085827 -0.8390224573061746 0.0 0.0 0.8390224573061746 0.5440967893085827 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5332044328016914 -0.845986425919841 0.0 0.0 0.845986425919841 0.5332044328016914 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5222229563517384 -0.852808996117683 0.0 0.0 0.852808996117683 0.5222229563517384 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5111541954058733 -0.8594890275733451 0.0 0.0 0.8594890275733451 0.5111541954058733 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
@@ -0,0 +1,82 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9999164298554373 0.012928004685808521 0.0 0.0 -0.012928004685808521 0.9999164298554373 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9996657333896874 0.025853848581176044 0.0 0.0 -0.025853848581176044 0.9996657333896874 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.99924795250423 0.03877537125681671 0.0 0.0 -0.03877537125681671 0.99924795250423 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9986631570270832 0.051690413005694553 0.0 0.0 -0.051690413005694553 0.9986631570270832 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.997911444701132 0.06459681520399763 0.0 0.0 -0.06459681520399763 0.997911444701132 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.996992941167792 0.07749242067193093 0.0 0.0 -0.07749242067193093 0.996992941167792 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9959077999460093 0.0903750740342681 0.0 0.0 -0.0903750740342681 0.9959077999460093 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9946562024066015 0.10324262208060146 0.0 0.0 -0.10324262208060146 0.9946562024066015 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.993238357741943 0.11609291412523022 0.0 0.0 -0.11609291412523022 0.993238357741943 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9916545029310012 0.12892380236662665 0.0 0.0 -0.12892380236662665 0.9916545029310012 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.989904902699727 0.14173314224642042 0.0 0.0 -0.14173314224642042 0.989904902699727 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.987989849476809 0.15451879280784048 0.0 0.0 -0.15451879280784048 0.987989849476809 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9859096633447965 0.16727861705355532 0.0 0.0 -0.16727861705355532 0.9859096633447965 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9836646919866011 0.18001048230285133 0.0 0.0 -0.18001048230285133 0.9836646919866011 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9812553106273847 0.19271226054808965 0.0 0.0 -0.19271226054808965 0.9812553106273847 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9786819219718442 0.20538182881038197 0.0 0.0 -0.20538182881038197 0.9786819219718442 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9759449561369036 0.21801706949442584 0.0 0.0 -0.21801706949442584 0.9759449561369036 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9730448705798238 0.23061587074244014 0.0 0.0 -0.23061587074244014 0.9730448705798238 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9699821500217435 0.24317612678714165 0.0 0.0 -0.24317612678714165 0.9699821500217435 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.966757306366662 0.25569573830370357 0.0 0.0 -0.25569573830370357 0.966757306366662 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9633708786158803 0.26817261276063736 0.0 0.0 -0.26817261276063736 0.9633708786158803 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9598234327779119 0.2806046647695387 0.0 0.0 -0.2806046647695387 0.9598234327779119 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9561155617738797 0.29298981643364064 0.0 0.0 -0.29298981643364064 0.9561155617738797 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9522478853384153 0.3053259976951131 0.0 0.0 -0.3053259976951131 0.9522478853384153 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9482210499160765 0.3176111466810532 0.0 0.0 -0.3176111466810532 0.9482210499160765 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9440357285533 0.3298432100481077 0.0 0.0 -0.3298432100481077 0.9440357285533 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9396926207859084 0.34202014332566866 0.0 0.0 -0.34202014332566866 0.9396926207859084 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9351924525221897 0.35413991125758754 0.0 0.0 -0.35413991125758754 0.9351924525221897 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9305359759215686 0.36620048814234796 0.0 0.0 -0.36620048814234796 0.9305359759215686 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9257239692688904 0.3781998581716424 0.0 0.0 -0.3781998581716424 0.9257239692688904 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9207572368443384 0.3901360157672949 0.0 0.0 -0.3901360157672949 0.9207572368443384 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9156366087890059 0.40200696591647384 0.0 0.0 -0.40200696591647384 0.9156366087890059 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9103629409661467 0.4138107245051391 0.0 0.0 -0.4138107245051391 0.9103629409661467 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.9049371148181253 0.4255453186496674 0.0 0.0 -0.4255453186496674 0.9049371148181253 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8993600372190931 0.4372087870266006 0.0 0.0 -0.4372087870266006 0.8993600372190931 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8936326403234123 0.4487991802004621 0.0 0.0 -0.4487991802004621 0.8936326403234123 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.887755881409856 0.4603145609495856 0.0 0.0 -0.4603145609495856 0.887755881409856 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.881730742721608 0.4717530045899035 0.0 0.0 -0.4717530045899035 0.881730742721608 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8755582313020909 0.4831125992966384 0.0 0.0 -0.4831125992966384 0.8755582313020909 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8692393788266478 0.4943914464238468 0.0 0.0 -0.4943914464238468 0.8692393788266478 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8627752414301085 0.5055876608217589 0.0 0.0 -0.5055876608217589 0.8627752414301085 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8561668995302665 0.5166993711518628 0.0 0.0 -0.5166993711518628 0.8561668995302665 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8494154576472973 0.5277247201996818 0.0 0.0 -0.5277247201996818 0.8494154576472973 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8425220442191496 0.5386618651851877 0.0 0.0 -0.5386618651851877 0.8425220442191496 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8354878114129365 0.549508978070806 0.0 0.0 -0.549508978070806 0.8354878114129365 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.828313934932363 0.5602642458669524 0.0 0.0 -0.5602642458669524 0.828313934932363 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8210016138212185 0.5709258709350582 0.0 0.0 -0.5709258709350582 0.8210016138212185 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8135520702629676 0.5814920712880266 0.0 0.0 -0.5814920712880266 0.8135520702629676 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.8059665493764744 0.5919610808880759 0.0 0.0 -0.5919610808880759 0.8059665493764744 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.798246319007893 0.6023311499419145 0.0 0.0 -0.6023311499419145 0.798246319007893 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7903926695187593 0.6126005451932028 0.0 0.0 -0.6126005451932028 0.7903926695187593 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7824069135703198 0.622767550212249 0.0 0.0 -0.622767550212249 0.7824069135703198 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7742903859041323 0.632830465682895 0.0 0.0 -0.632830465682895 0.7742903859041323 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7660444431189781 0.6427876096865393 0.0 0.0 -0.6427876096865393 0.7660444431189781 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7576704634441179 0.6526373179832544 0.0 0.0 -0.6526373179832544 0.7576704634441179 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.749169846508936 0.6623779442899478 0.0 0.0 -0.6623779442899478 0.749169846508936 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7405440131090046 0.6720078605555224 0.0 0.0 -0.6720078605555224 0.7405440131090046 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7317944049686121 0.6815254572329892 0.0 0.0 -0.6815254572329892 0.7317944049686121 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7229224844997929 0.6909291435484877 0.0 0.0 -0.6909291435484877 0.7229224844997929 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7139297345578991 0.7002173477671684 0.0 0.0 -0.7002173477671684 0.7139297345578991 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.7048176581937561 0.7093885174558928 0.0 0.0 -0.7093885174558928 0.7048176581937561 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.695587778402442 0.7184411197427074 0.0 0.0 -0.7184411197427074 0.695587778402442 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6862416378687336 0.7273736415730486 0.0 0.0 -0.7273736415730486 0.6862416378687336 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6767807987092621 0.7361845899626351 0.0 0.0 -0.7361845899626351 0.6767807987092621 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6672068422114197 0.7448724922470058 0.0 0.0 -0.7448724922470058 0.6672068422114197 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6575213685690637 0.7534358963276606 0.0 0.0 -0.7534358963276606 0.6575213685690637 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.647725996615059 0.761873370914766 0.0 0.0 -0.761873370914766 0.647725996615059 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6378223635507061 0.7701835057663796 0.0 0.0 -0.7701835057663796 0.6378223635507061 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6278121246720987 0.7783649119241599 0.0 0.0 -0.7783649119241599 0.6278121246720987 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6176969530934572 0.7864162219455162 0.0 0.0 -0.7864162219455162 0.6176969530934572 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.6074785394674836 0.7943360901321637 0.0 0.0 -0.7943360901321637 0.6074785394674836 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5971585917027863 0.8021231927550437 0.0 0.0 -0.8021231927550437 0.5971585917027863 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5867388346784178 0.8097762282755726 0.0 0.0 -0.8097762282755726 0.5867388346784178 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5762210099555805 0.8172939175631805 0.0 0.0 -0.8172939175631805 0.5762210099555805 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5656068754865388 0.8246750041091067 0.0 0.0 -0.8246750041091067 0.5656068754865388 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.554898205320797 0.8319182542364115 0.0 0.0 -0.8319182542364115 0.554898205320797 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5440967893085827 0.8390224573061746 0.0 0.0 -0.8390224573061746 0.5440967893085827 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5332044328016914 0.845986425919841 0.0 0.0 -0.845986425919841 0.5332044328016914 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5222229563517384 0.852808996117683 0.0 0.0 -0.852808996117683 0.5222229563517384 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 0.5111541954058733 0.8594890275733451 0.0 0.0 -0.8594890275733451 0.5111541954058733 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
@@ -0,0 +1,82 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.018518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.037037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.05555555555555555 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.07407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.09259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.1111111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.12962962962962962 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.14814814814814814 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.16666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.18518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.2222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.24074074074074073 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.25925925925925924 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.2777777777777778 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.31481481481481477 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.35185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.37037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.38888888888888884 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.42592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.4629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.48148148148148145 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5185185185185185 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.537037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5740740740740741 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.5925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.611111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.6296296296296295 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.6481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.6666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.6851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.7962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8148148148148148 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8333333333333334 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8703703703703705 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.8888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9259259259259258 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.9814814814814815 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.0185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.0555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.0925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1111111111111112 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1296296296296298 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1666666666666667 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.1851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.2407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.2777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3148148148148149 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3703703703703702 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.3888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.425925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.462962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -1.4814814814814814 0.0 0.0 1.0 0.0
|
||||
@@ -0,0 +1,82 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.018518518518518517 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.037037037037037035 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.05555555555555555 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.07407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.09259259259259259 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.1111111111111111 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.12962962962962962 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.14814814814814814 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.16666666666666666 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.18518518518518517 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.24074074074074073 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.25925925925925924 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2777777777777778 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.31481481481481477 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.3333333333333333 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.35185185185185186 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.37037037037037035 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.38888888888888884 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.42592592592592593 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4629629629629629 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.48148148148148145 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5185185185185185 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.537037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5555555555555556 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5740740740740741 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5925925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.611111111111111 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6296296296296295 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6481481481481481 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6666666666666666 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6851851851851851 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7592592592592593 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7777777777777777 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8148148148148148 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8333333333333334 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8518518518518519 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8703703703703705 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8888888888888888 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9259259259259258 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9629629629629629 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9814814814814815 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0185185185185186 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0555555555555556 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0925925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1111111111111112 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1296296296296298 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1481481481481481 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1666666666666667 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1851851851851851 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.259259259259259 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2777777777777777 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3148148148148149 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3333333333333333 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3518518518518519 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3703703703703702 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3888888888888888 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.425925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.462962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4814814814814814 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
@@ -0,0 +1,82 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 -0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.018518518518518517 0.0 1.0 0.0 -0.018518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.037037037037037035 0.0 1.0 0.0 -0.037037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.05555555555555555 0.0 1.0 0.0 -0.05555555555555555 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.07407407407407407 0.0 1.0 0.0 -0.07407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.09259259259259259 0.0 1.0 0.0 -0.09259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.1111111111111111 0.0 1.0 0.0 -0.1111111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.12962962962962962 0.0 1.0 0.0 -0.12962962962962962 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.14814814814814814 0.0 1.0 0.0 -0.14814814814814814 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.16666666666666666 0.0 1.0 0.0 -0.16666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.18518518518518517 0.0 1.0 0.0 -0.18518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2037037037037037 0.0 1.0 0.0 -0.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2222222222222222 0.0 1.0 0.0 -0.2222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.24074074074074073 0.0 1.0 0.0 -0.24074074074074073 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.25925925925925924 0.0 1.0 0.0 -0.25925925925925924 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2777777777777778 0.0 1.0 0.0 -0.2777777777777778 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2962962962962963 0.0 1.0 0.0 -0.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.31481481481481477 0.0 1.0 0.0 -0.31481481481481477 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.3333333333333333 0.0 1.0 0.0 -0.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.35185185185185186 0.0 1.0 0.0 -0.35185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.37037037037037035 0.0 1.0 0.0 -0.37037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.38888888888888884 0.0 1.0 0.0 -0.38888888888888884 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4074074074074074 0.0 1.0 0.0 -0.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.42592592592592593 0.0 1.0 0.0 -0.42592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4444444444444444 0.0 1.0 0.0 -0.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4629629629629629 0.0 1.0 0.0 -0.4629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.48148148148148145 0.0 1.0 0.0 -0.48148148148148145 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5 0.0 1.0 0.0 -0.5 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5185185185185185 0.0 1.0 0.0 -0.5185185185185185 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.537037037037037 0.0 1.0 0.0 -0.537037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5555555555555556 0.0 1.0 0.0 -0.5555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5740740740740741 0.0 1.0 0.0 -0.5740740740740741 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5925925925925926 0.0 1.0 0.0 -0.5925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.611111111111111 0.0 1.0 0.0 -0.611111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6296296296296295 0.0 1.0 0.0 -0.6296296296296295 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6481481481481481 0.0 1.0 0.0 -0.6481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6666666666666666 0.0 1.0 0.0 -0.6666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6851851851851851 0.0 1.0 0.0 -0.6851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7037037037037037 0.0 1.0 0.0 -0.7037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7222222222222222 0.0 1.0 0.0 -0.7222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7407407407407407 0.0 1.0 0.0 -0.7407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7592592592592593 0.0 1.0 0.0 -0.7592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7777777777777777 0.0 1.0 0.0 -0.7777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7962962962962963 0.0 1.0 0.0 -0.7962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8148148148148148 0.0 1.0 0.0 -0.8148148148148148 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8333333333333334 0.0 1.0 0.0 -0.8333333333333334 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8518518518518519 0.0 1.0 0.0 -0.8518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8703703703703705 0.0 1.0 0.0 -0.8703703703703705 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8888888888888888 0.0 1.0 0.0 -0.8888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9074074074074074 0.0 1.0 0.0 -0.9074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9259259259259258 0.0 1.0 0.0 -0.9259259259259258 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9444444444444444 0.0 1.0 0.0 -0.9444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9629629629629629 0.0 1.0 0.0 -0.9629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9814814814814815 0.0 1.0 0.0 -0.9814814814814815 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0 0.0 1.0 0.0 -1.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0185185185185186 0.0 1.0 0.0 -1.0185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.037037037037037 0.0 1.0 0.0 -1.037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0555555555555556 0.0 1.0 0.0 -1.0555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.074074074074074 0.0 1.0 0.0 -1.074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0925925925925926 0.0 1.0 0.0 -1.0925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1111111111111112 0.0 1.0 0.0 -1.1111111111111112 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1296296296296298 0.0 1.0 0.0 -1.1296296296296298 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1481481481481481 0.0 1.0 0.0 -1.1481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1666666666666667 0.0 1.0 0.0 -1.1666666666666667 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1851851851851851 0.0 1.0 0.0 -1.1851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2037037037037037 0.0 1.0 0.0 -1.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.222222222222222 0.0 1.0 0.0 -1.222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2407407407407407 0.0 1.0 0.0 -1.2407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.259259259259259 0.0 1.0 0.0 -1.259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2777777777777777 0.0 1.0 0.0 -1.2777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2962962962962963 0.0 1.0 0.0 -1.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3148148148148149 0.0 1.0 0.0 -1.3148148148148149 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3333333333333333 0.0 1.0 0.0 -1.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3518518518518519 0.0 1.0 0.0 -1.3518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3703703703703702 0.0 1.0 0.0 -1.3703703703703702 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3888888888888888 0.0 1.0 0.0 -1.3888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4074074074074074 0.0 1.0 0.0 -1.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.425925925925926 0.0 1.0 0.0 -1.425925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4444444444444444 0.0 1.0 0.0 -1.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.462962962962963 0.0 1.0 0.0 -1.462962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4814814814814814 0.0 1.0 0.0 -1.4814814814814814 0.0 0.0 1.0 0.0
|
||||
@@ -0,0 +1,82 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.018518518518518517 0.0 1.0 0.0 0.018518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.037037037037037035 0.0 1.0 0.0 0.037037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.05555555555555555 0.0 1.0 0.0 0.05555555555555555 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.07407407407407407 0.0 1.0 0.0 0.07407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.09259259259259259 0.0 1.0 0.0 0.09259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.1111111111111111 0.0 1.0 0.0 0.1111111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.12962962962962962 0.0 1.0 0.0 0.12962962962962962 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.14814814814814814 0.0 1.0 0.0 0.14814814814814814 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.16666666666666666 0.0 1.0 0.0 0.16666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.18518518518518517 0.0 1.0 0.0 0.18518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2037037037037037 0.0 1.0 0.0 0.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2222222222222222 0.0 1.0 0.0 0.2222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.24074074074074073 0.0 1.0 0.0 0.24074074074074073 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.25925925925925924 0.0 1.0 0.0 0.25925925925925924 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2777777777777778 0.0 1.0 0.0 0.2777777777777778 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.2962962962962963 0.0 1.0 0.0 0.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.31481481481481477 0.0 1.0 0.0 0.31481481481481477 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.3333333333333333 0.0 1.0 0.0 0.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.35185185185185186 0.0 1.0 0.0 0.35185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.37037037037037035 0.0 1.0 0.0 0.37037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.38888888888888884 0.0 1.0 0.0 0.38888888888888884 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4074074074074074 0.0 1.0 0.0 0.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.42592592592592593 0.0 1.0 0.0 0.42592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4444444444444444 0.0 1.0 0.0 0.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.4629629629629629 0.0 1.0 0.0 0.4629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.48148148148148145 0.0 1.0 0.0 0.48148148148148145 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5 0.0 1.0 0.0 0.5 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5185185185185185 0.0 1.0 0.0 0.5185185185185185 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.537037037037037 0.0 1.0 0.0 0.537037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5555555555555556 0.0 1.0 0.0 0.5555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5740740740740741 0.0 1.0 0.0 0.5740740740740741 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.5925925925925926 0.0 1.0 0.0 0.5925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.611111111111111 0.0 1.0 0.0 0.611111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6296296296296295 0.0 1.0 0.0 0.6296296296296295 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6481481481481481 0.0 1.0 0.0 0.6481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6666666666666666 0.0 1.0 0.0 0.6666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.6851851851851851 0.0 1.0 0.0 0.6851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7037037037037037 0.0 1.0 0.0 0.7037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7222222222222222 0.0 1.0 0.0 0.7222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7407407407407407 0.0 1.0 0.0 0.7407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7592592592592593 0.0 1.0 0.0 0.7592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7777777777777777 0.0 1.0 0.0 0.7777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.7962962962962963 0.0 1.0 0.0 0.7962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8148148148148148 0.0 1.0 0.0 0.8148148148148148 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8333333333333334 0.0 1.0 0.0 0.8333333333333334 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8518518518518519 0.0 1.0 0.0 0.8518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8703703703703705 0.0 1.0 0.0 0.8703703703703705 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.8888888888888888 0.0 1.0 0.0 0.8888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9074074074074074 0.0 1.0 0.0 0.9074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9259259259259258 0.0 1.0 0.0 0.9259259259259258 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9444444444444444 0.0 1.0 0.0 0.9444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9629629629629629 0.0 1.0 0.0 0.9629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.9814814814814815 0.0 1.0 0.0 0.9814814814814815 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0 0.0 1.0 0.0 1.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0185185185185186 0.0 1.0 0.0 1.0185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.037037037037037 0.0 1.0 0.0 1.037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0555555555555556 0.0 1.0 0.0 1.0555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.074074074074074 0.0 1.0 0.0 1.074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.0925925925925926 0.0 1.0 0.0 1.0925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1111111111111112 0.0 1.0 0.0 1.1111111111111112 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1296296296296298 0.0 1.0 0.0 1.1296296296296298 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1481481481481481 0.0 1.0 0.0 1.1481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1666666666666667 0.0 1.0 0.0 1.1666666666666667 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.1851851851851851 0.0 1.0 0.0 1.1851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2037037037037037 0.0 1.0 0.0 1.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.222222222222222 0.0 1.0 0.0 1.222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2407407407407407 0.0 1.0 0.0 1.2407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.259259259259259 0.0 1.0 0.0 1.259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2777777777777777 0.0 1.0 0.0 1.2777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.2962962962962963 0.0 1.0 0.0 1.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3148148148148149 0.0 1.0 0.0 1.3148148148148149 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3333333333333333 0.0 1.0 0.0 1.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3518518518518519 0.0 1.0 0.0 1.3518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3703703703703702 0.0 1.0 0.0 1.3703703703703702 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.3888888888888888 0.0 1.0 0.0 1.3888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4074074074074074 0.0 1.0 0.0 1.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.425925925925926 0.0 1.0 0.0 1.425925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4444444444444444 0.0 1.0 0.0 1.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.462962962962963 0.0 1.0 0.0 1.462962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 1.4814814814814814 0.0 1.0 0.0 1.4814814814814814 0.0 0.0 1.0 0.0
|
||||
@@ -0,0 +1,82 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.018518518518518517 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.037037037037037035 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.05555555555555555 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.07407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.09259259259259259 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.1111111111111111 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.12962962962962962 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.14814814814814814 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.16666666666666666 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.18518518518518517 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.24074074074074073 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.25925925925925924 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2777777777777778 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.31481481481481477 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.3333333333333333 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.35185185185185186 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.37037037037037035 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.38888888888888884 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.42592592592592593 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4629629629629629 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.48148148148148145 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5185185185185185 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.537037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5555555555555556 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5740740740740741 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5925925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.611111111111111 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6296296296296295 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6481481481481481 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6666666666666666 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6851851851851851 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7592592592592593 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7777777777777777 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8148148148148148 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8333333333333334 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8518518518518519 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8703703703703705 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8888888888888888 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9259259259259258 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9629629629629629 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9814814814814815 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0185185185185186 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0555555555555556 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0925925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1111111111111112 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1296296296296298 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1481481481481481 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1666666666666667 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1851851851851851 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2037037037037037 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.222222222222222 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2407407407407407 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.259259259259259 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2777777777777777 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2962962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3148148148148149 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3333333333333333 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3518518518518519 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3703703703703702 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3888888888888888 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4074074074074074 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.425925925925926 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4444444444444444 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.462962962962963 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4814814814814814 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
@@ -0,0 +1,82 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.0 0.0 1.0 0.0 -0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.018518518518518517 0.0 1.0 0.0 -0.018518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.037037037037037035 0.0 1.0 0.0 -0.037037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.05555555555555555 0.0 1.0 0.0 -0.05555555555555555 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.07407407407407407 0.0 1.0 0.0 -0.07407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.09259259259259259 0.0 1.0 0.0 -0.09259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.1111111111111111 0.0 1.0 0.0 -0.1111111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.12962962962962962 0.0 1.0 0.0 -0.12962962962962962 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.14814814814814814 0.0 1.0 0.0 -0.14814814814814814 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.16666666666666666 0.0 1.0 0.0 -0.16666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.18518518518518517 0.0 1.0 0.0 -0.18518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2037037037037037 0.0 1.0 0.0 -0.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2222222222222222 0.0 1.0 0.0 -0.2222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.24074074074074073 0.0 1.0 0.0 -0.24074074074074073 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.25925925925925924 0.0 1.0 0.0 -0.25925925925925924 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2777777777777778 0.0 1.0 0.0 -0.2777777777777778 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2962962962962963 0.0 1.0 0.0 -0.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.31481481481481477 0.0 1.0 0.0 -0.31481481481481477 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.3333333333333333 0.0 1.0 0.0 -0.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.35185185185185186 0.0 1.0 0.0 -0.35185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.37037037037037035 0.0 1.0 0.0 -0.37037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.38888888888888884 0.0 1.0 0.0 -0.38888888888888884 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4074074074074074 0.0 1.0 0.0 -0.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.42592592592592593 0.0 1.0 0.0 -0.42592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4444444444444444 0.0 1.0 0.0 -0.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4629629629629629 0.0 1.0 0.0 -0.4629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.48148148148148145 0.0 1.0 0.0 -0.48148148148148145 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5 0.0 1.0 0.0 -0.5 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5185185185185185 0.0 1.0 0.0 -0.5185185185185185 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.537037037037037 0.0 1.0 0.0 -0.537037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5555555555555556 0.0 1.0 0.0 -0.5555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5740740740740741 0.0 1.0 0.0 -0.5740740740740741 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5925925925925926 0.0 1.0 0.0 -0.5925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.611111111111111 0.0 1.0 0.0 -0.611111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6296296296296295 0.0 1.0 0.0 -0.6296296296296295 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6481481481481481 0.0 1.0 0.0 -0.6481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6666666666666666 0.0 1.0 0.0 -0.6666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6851851851851851 0.0 1.0 0.0 -0.6851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7037037037037037 0.0 1.0 0.0 -0.7037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7222222222222222 0.0 1.0 0.0 -0.7222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7407407407407407 0.0 1.0 0.0 -0.7407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7592592592592593 0.0 1.0 0.0 -0.7592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7777777777777777 0.0 1.0 0.0 -0.7777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7962962962962963 0.0 1.0 0.0 -0.7962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8148148148148148 0.0 1.0 0.0 -0.8148148148148148 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8333333333333334 0.0 1.0 0.0 -0.8333333333333334 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8518518518518519 0.0 1.0 0.0 -0.8518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8703703703703705 0.0 1.0 0.0 -0.8703703703703705 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8888888888888888 0.0 1.0 0.0 -0.8888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9074074074074074 0.0 1.0 0.0 -0.9074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9259259259259258 0.0 1.0 0.0 -0.9259259259259258 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9444444444444444 0.0 1.0 0.0 -0.9444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9629629629629629 0.0 1.0 0.0 -0.9629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9814814814814815 0.0 1.0 0.0 -0.9814814814814815 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0 0.0 1.0 0.0 -1.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0185185185185186 0.0 1.0 0.0 -1.0185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.037037037037037 0.0 1.0 0.0 -1.037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0555555555555556 0.0 1.0 0.0 -1.0555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.074074074074074 0.0 1.0 0.0 -1.074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0925925925925926 0.0 1.0 0.0 -1.0925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1111111111111112 0.0 1.0 0.0 -1.1111111111111112 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1296296296296298 0.0 1.0 0.0 -1.1296296296296298 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1481481481481481 0.0 1.0 0.0 -1.1481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1666666666666667 0.0 1.0 0.0 -1.1666666666666667 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1851851851851851 0.0 1.0 0.0 -1.1851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2037037037037037 0.0 1.0 0.0 -1.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.222222222222222 0.0 1.0 0.0 -1.222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2407407407407407 0.0 1.0 0.0 -1.2407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.259259259259259 0.0 1.0 0.0 -1.259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2777777777777777 0.0 1.0 0.0 -1.2777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2962962962962963 0.0 1.0 0.0 -1.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3148148148148149 0.0 1.0 0.0 -1.3148148148148149 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3333333333333333 0.0 1.0 0.0 -1.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3518518518518519 0.0 1.0 0.0 -1.3518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3703703703703702 0.0 1.0 0.0 -1.3703703703703702 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3888888888888888 0.0 1.0 0.0 -1.3888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4074074074074074 0.0 1.0 0.0 -1.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.425925925925926 0.0 1.0 0.0 -1.425925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4444444444444444 0.0 1.0 0.0 -1.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.462962962962963 0.0 1.0 0.0 -1.462962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4814814814814814 0.0 1.0 0.0 -1.4814814814814814 0.0 0.0 1.0 0.0
|
||||
@@ -0,0 +1,82 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.018518518518518517 0.0 1.0 0.0 0.018518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.037037037037037035 0.0 1.0 0.0 0.037037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.05555555555555555 0.0 1.0 0.0 0.05555555555555555 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.07407407407407407 0.0 1.0 0.0 0.07407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.09259259259259259 0.0 1.0 0.0 0.09259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.1111111111111111 0.0 1.0 0.0 0.1111111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.12962962962962962 0.0 1.0 0.0 0.12962962962962962 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.14814814814814814 0.0 1.0 0.0 0.14814814814814814 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.16666666666666666 0.0 1.0 0.0 0.16666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.18518518518518517 0.0 1.0 0.0 0.18518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2037037037037037 0.0 1.0 0.0 0.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2222222222222222 0.0 1.0 0.0 0.2222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.24074074074074073 0.0 1.0 0.0 0.24074074074074073 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.25925925925925924 0.0 1.0 0.0 0.25925925925925924 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2777777777777778 0.0 1.0 0.0 0.2777777777777778 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.2962962962962963 0.0 1.0 0.0 0.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.31481481481481477 0.0 1.0 0.0 0.31481481481481477 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.3333333333333333 0.0 1.0 0.0 0.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.35185185185185186 0.0 1.0 0.0 0.35185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.37037037037037035 0.0 1.0 0.0 0.37037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.38888888888888884 0.0 1.0 0.0 0.38888888888888884 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4074074074074074 0.0 1.0 0.0 0.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.42592592592592593 0.0 1.0 0.0 0.42592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4444444444444444 0.0 1.0 0.0 0.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.4629629629629629 0.0 1.0 0.0 0.4629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.48148148148148145 0.0 1.0 0.0 0.48148148148148145 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5 0.0 1.0 0.0 0.5 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5185185185185185 0.0 1.0 0.0 0.5185185185185185 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.537037037037037 0.0 1.0 0.0 0.537037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5555555555555556 0.0 1.0 0.0 0.5555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5740740740740741 0.0 1.0 0.0 0.5740740740740741 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.5925925925925926 0.0 1.0 0.0 0.5925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.611111111111111 0.0 1.0 0.0 0.611111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6296296296296295 0.0 1.0 0.0 0.6296296296296295 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6481481481481481 0.0 1.0 0.0 0.6481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6666666666666666 0.0 1.0 0.0 0.6666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.6851851851851851 0.0 1.0 0.0 0.6851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7037037037037037 0.0 1.0 0.0 0.7037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7222222222222222 0.0 1.0 0.0 0.7222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7407407407407407 0.0 1.0 0.0 0.7407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7592592592592593 0.0 1.0 0.0 0.7592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7777777777777777 0.0 1.0 0.0 0.7777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.7962962962962963 0.0 1.0 0.0 0.7962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8148148148148148 0.0 1.0 0.0 0.8148148148148148 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8333333333333334 0.0 1.0 0.0 0.8333333333333334 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8518518518518519 0.0 1.0 0.0 0.8518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8703703703703705 0.0 1.0 0.0 0.8703703703703705 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.8888888888888888 0.0 1.0 0.0 0.8888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9074074074074074 0.0 1.0 0.0 0.9074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9259259259259258 0.0 1.0 0.0 0.9259259259259258 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9444444444444444 0.0 1.0 0.0 0.9444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9629629629629629 0.0 1.0 0.0 0.9629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -0.9814814814814815 0.0 1.0 0.0 0.9814814814814815 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0 0.0 1.0 0.0 1.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0185185185185186 0.0 1.0 0.0 1.0185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.037037037037037 0.0 1.0 0.0 1.037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0555555555555556 0.0 1.0 0.0 1.0555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.074074074074074 0.0 1.0 0.0 1.074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.0925925925925926 0.0 1.0 0.0 1.0925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1111111111111112 0.0 1.0 0.0 1.1111111111111112 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1296296296296298 0.0 1.0 0.0 1.1296296296296298 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1481481481481481 0.0 1.0 0.0 1.1481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1666666666666667 0.0 1.0 0.0 1.1666666666666667 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.1851851851851851 0.0 1.0 0.0 1.1851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2037037037037037 0.0 1.0 0.0 1.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.222222222222222 0.0 1.0 0.0 1.222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2407407407407407 0.0 1.0 0.0 1.2407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.259259259259259 0.0 1.0 0.0 1.259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2777777777777777 0.0 1.0 0.0 1.2777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.2962962962962963 0.0 1.0 0.0 1.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3148148148148149 0.0 1.0 0.0 1.3148148148148149 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3333333333333333 0.0 1.0 0.0 1.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3518518518518519 0.0 1.0 0.0 1.3518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3703703703703702 0.0 1.0 0.0 1.3703703703703702 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.3888888888888888 0.0 1.0 0.0 1.3888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4074074074074074 0.0 1.0 0.0 1.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.425925925925926 0.0 1.0 0.0 1.425925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4444444444444444 0.0 1.0 0.0 1.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.462962962962963 0.0 1.0 0.0 1.462962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 -1.4814814814814814 0.0 1.0 0.0 1.4814814814814814 0.0 0.0 1.0 0.0
|
||||
@@ -0,0 +1,82 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.018518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.037037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.05555555555555555 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.07407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.09259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.1111111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.12962962962962962 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.14814814814814814 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.16666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.18518518518518517 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.2222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.24074074074074073 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.25925925925925924 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.2777777777777778 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.31481481481481477 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.35185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.37037037037037035 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.38888888888888884 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.42592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.4629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.48148148148148145 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5185185185185185 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.537037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5740740740740741 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.5925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.611111111111111 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.6296296296296295 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.6481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.6666666666666666 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.6851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7592592592592593 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.7962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8148148148148148 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8333333333333334 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8703703703703705 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.8888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9259259259259258 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9629629629629629 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.9814814814814815 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.0185185185185186 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.0555555555555556 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.0925925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1111111111111112 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1296296296296298 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1481481481481481 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1666666666666667 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.1851851851851851 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.2037037037037037 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.222222222222222 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.2407407407407407 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.259259259259259 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.2777777777777777 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.2962962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3148148148148149 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3333333333333333 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3518518518518519 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3703703703703702 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.3888888888888888 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.4074074074074074 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.425925925925926 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.4444444444444444 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.462962962962963 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 1.4814814814814814 0.0 0.0 1.0 0.0
|
||||
@@ -0,0 +1,82 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.037037037037037035
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.07407407407407407
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.1111111111111111
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.14814814814814814
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.18518518518518517
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.2222222222222222
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.25925925925925924
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.2962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.3333333333333333
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.37037037037037035
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.4074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.4444444444444444
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.48148148148148145
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.5185185185185185
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.5555555555555556
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.5925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.6296296296296295
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.6666666666666666
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.7037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.7407407407407407
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.7777777777777777
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.8148148148148148
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.8518518518518519
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.8888888888888888
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.9259259259259258
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -0.9629629629629629
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.1111111111111112
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.1481481481481481
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.1851851851851851
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.222222222222222
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.259259259259259
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.2962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.3333333333333333
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.3703703703703702
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.4074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.4444444444444444
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.4814814814814814
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.5185185185185186
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.5555555555555554
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.5925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.6296296296296295
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.6666666666666667
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.7037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.740740740740741
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.7777777777777777
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.8148148148148149
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.8518518518518516
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.8888888888888888
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.9259259259259258
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -1.962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.111111111111111
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.148148148148148
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.185185185185185
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.2222222222222223
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.2592592592592595
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.2962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.3333333333333335
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.3703703703703702
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.4074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.444444444444444
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.4814814814814814
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.518518518518518
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.5555555555555554
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.5925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.6296296296296298
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.6666666666666665
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.7037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.7407407407407405
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.7777777777777777
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.814814814814815
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.851851851851852
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.888888888888889
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 -2.962962962962963
|
||||
@@ -0,0 +1,82 @@
|
||||
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.037037037037037035
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.07407407407407407
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.1111111111111111
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.14814814814814814
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.18518518518518517
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.2222222222222222
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.25925925925925924
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.2962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.3333333333333333
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.37037037037037035
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.4074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.4444444444444444
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.48148148148148145
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.5185185185185185
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.5555555555555556
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.5925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.6296296296296295
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.6666666666666666
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.7037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.7407407407407407
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.7777777777777777
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.8148148148148148
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.8518518518518519
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.8888888888888888
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.9259259259259258
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 0.9629629629629629
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.1111111111111112
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.1481481481481481
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.1851851851851851
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.222222222222222
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.259259259259259
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.2962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.3333333333333333
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.3703703703703702
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.4074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.4444444444444444
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.4814814814814814
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.5185185185185186
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.5555555555555554
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.5925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.6296296296296295
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.6666666666666667
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.7037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.740740740740741
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.7777777777777777
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.8148148148148149
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.8518518518518516
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.8888888888888888
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.9259259259259258
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 1.962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.0
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.111111111111111
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.148148148148148
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.185185185185185
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.2222222222222223
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.2592592592592595
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.2962962962962963
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.3333333333333335
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.3703703703703702
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.4074074074074074
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.444444444444444
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.4814814814814814
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.518518518518518
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.5555555555555554
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.5925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.6296296296296298
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.6666666666666665
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.7037037037037037
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.7407407407407405
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.7777777777777777
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.814814814814815
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.851851851851852
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.888888888888889
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.925925925925926
|
||||
0 0.532139961 0.946026558 0.5 0.5 0 0 1.0 0.0 0.0 0.0 0.0 1.0 0.0 0.0 0.0 0.0 1.0 2.962962962962963
|
||||

|
After Width: | Height: | Size: 43 KiB |

|
After Width: | Height: | Size: 11 KiB |

|
After Width: | Height: | Size: 42 KiB |

|
After Width: | Height: | Size: 129 KiB |

|
After Width: | Height: | Size: 226 KiB |
@@ -1,149 +0,0 @@
|
||||
import io
|
||||
import gc
|
||||
import base64
|
||||
import torch
|
||||
import gradio as gr
|
||||
import tempfile
|
||||
import hashlib
|
||||
import os
|
||||
|
||||
from fastapi import FastAPI
|
||||
from io import BytesIO
|
||||
from PIL import Image
|
||||
|
||||
# Function to encode a file to Base64
|
||||
def encode_file_to_base64(file_path):
|
||||
with open(file_path, "rb") as file:
|
||||
# Encode the data to Base64
|
||||
file_base64 = base64.b64encode(file.read())
|
||||
return file_base64
|
||||
|
||||
def update_edition_api(_: gr.Blocks, app: FastAPI, controller):
|
||||
@app.post("/cogvideox_fun/update_edition")
|
||||
def _update_edition_api(
|
||||
datas: dict,
|
||||
):
|
||||
edition = datas.get('edition', 'v2')
|
||||
|
||||
try:
|
||||
controller.update_edition(
|
||||
edition
|
||||
)
|
||||
comment = "Success"
|
||||
except Exception as e:
|
||||
torch.cuda.empty_cache()
|
||||
comment = f"Error. error information is {str(e)}"
|
||||
|
||||
return {"message": comment}
|
||||
|
||||
def update_diffusion_transformer_api(_: gr.Blocks, app: FastAPI, controller):
|
||||
@app.post("/cogvideox_fun/update_diffusion_transformer")
|
||||
def _update_diffusion_transformer_api(
|
||||
datas: dict,
|
||||
):
|
||||
diffusion_transformer_path = datas.get('diffusion_transformer_path', 'none')
|
||||
|
||||
try:
|
||||
controller.update_diffusion_transformer(
|
||||
diffusion_transformer_path
|
||||
)
|
||||
comment = "Success"
|
||||
except Exception as e:
|
||||
torch.cuda.empty_cache()
|
||||
comment = f"Error. error information is {str(e)}"
|
||||
|
||||
return {"message": comment}
|
||||
|
||||
def save_base64_video(base64_string):
|
||||
video_data = base64.b64decode(base64_string)
|
||||
|
||||
md5_hash = hashlib.md5(video_data).hexdigest()
|
||||
filename = f"{md5_hash}.mp4"
|
||||
|
||||
temp_dir = tempfile.gettempdir()
|
||||
file_path = os.path.join(temp_dir, filename)
|
||||
|
||||
with open(file_path, 'wb') as video_file:
|
||||
video_file.write(video_data)
|
||||
|
||||
return file_path
|
||||
|
||||
def infer_forward_api(_: gr.Blocks, app: FastAPI, controller):
|
||||
@app.post("/cogvideox_fun/infer_forward")
|
||||
def _infer_forward_api(
|
||||
datas: dict,
|
||||
):
|
||||
base_model_path = datas.get('base_model_path', 'none')
|
||||
lora_model_path = datas.get('lora_model_path', 'none')
|
||||
lora_alpha_slider = datas.get('lora_alpha_slider', 0.55)
|
||||
prompt_textbox = datas.get('prompt_textbox', None)
|
||||
negative_prompt_textbox = datas.get('negative_prompt_textbox', 'The video is not of a high quality, it has a low resolution, and the audio quality is not clear. Strange motion trajectory, a poor composition and deformed video, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera. Deformation, low-resolution, blurry, ugly, distortion.')
|
||||
sampler_dropdown = datas.get('sampler_dropdown', 'Euler')
|
||||
sample_step_slider = datas.get('sample_step_slider', 30)
|
||||
resize_method = datas.get('resize_method', "Generate by")
|
||||
width_slider = datas.get('width_slider', 672)
|
||||
height_slider = datas.get('height_slider', 384)
|
||||
base_resolution = datas.get('base_resolution', 512)
|
||||
is_image = datas.get('is_image', False)
|
||||
generation_method = datas.get('generation_method', False)
|
||||
length_slider = datas.get('length_slider', 144)
|
||||
overlap_video_length = datas.get('overlap_video_length', 4)
|
||||
partial_video_length = datas.get('partial_video_length', 72)
|
||||
cfg_scale_slider = datas.get('cfg_scale_slider', 6)
|
||||
start_image = datas.get('start_image', None)
|
||||
end_image = datas.get('end_image', None)
|
||||
validation_video = datas.get('validation_video', None)
|
||||
denoise_strength = datas.get('denoise_strength', 0.70)
|
||||
seed_textbox = datas.get("seed_textbox", 43)
|
||||
|
||||
generation_method = "Image Generation" if is_image else generation_method
|
||||
|
||||
if start_image is not None:
|
||||
start_image = base64.b64decode(start_image)
|
||||
start_image = [Image.open(BytesIO(start_image))]
|
||||
|
||||
if end_image is not None:
|
||||
end_image = base64.b64decode(end_image)
|
||||
end_image = [Image.open(BytesIO(end_image))]
|
||||
|
||||
if validation_video is not None:
|
||||
validation_video = save_base64_video(validation_video)
|
||||
|
||||
try:
|
||||
save_sample_path, comment = controller.generate(
|
||||
"",
|
||||
base_model_path,
|
||||
lora_model_path,
|
||||
lora_alpha_slider,
|
||||
prompt_textbox,
|
||||
negative_prompt_textbox,
|
||||
sampler_dropdown,
|
||||
sample_step_slider,
|
||||
resize_method,
|
||||
width_slider,
|
||||
height_slider,
|
||||
base_resolution,
|
||||
generation_method,
|
||||
length_slider,
|
||||
overlap_video_length,
|
||||
partial_video_length,
|
||||
cfg_scale_slider,
|
||||
start_image,
|
||||
end_image,
|
||||
validation_video,
|
||||
denoise_strength,
|
||||
seed_textbox,
|
||||
is_api = True,
|
||||
)
|
||||
except Exception as e:
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.ipc_collect()
|
||||
save_sample_path = ""
|
||||
comment = f"Error. error information is {str(e)}"
|
||||
return {"message": comment}
|
||||
|
||||
if save_sample_path != "":
|
||||
return {"message": comment, "save_sample_path": save_sample_path, "base64_encoding": encode_file_to_base64(save_sample_path)}
|
||||
else:
|
||||
return {"message": comment, "save_sample_path": save_sample_path}
|
||||
@@ -1,96 +0,0 @@
|
||||
import base64
|
||||
import json
|
||||
import sys
|
||||
import time
|
||||
from datetime import datetime
|
||||
from io import BytesIO
|
||||
|
||||
import cv2
|
||||
import requests
|
||||
import base64
|
||||
|
||||
|
||||
def post_diffusion_transformer(diffusion_transformer_path, url='http://127.0.0.1:7860'):
|
||||
datas = json.dumps({
|
||||
"diffusion_transformer_path": diffusion_transformer_path
|
||||
})
|
||||
r = requests.post(f'{url}/cogvideox_fun/update_diffusion_transformer', data=datas, timeout=1500)
|
||||
data = r.content.decode('utf-8')
|
||||
return data
|
||||
|
||||
def post_update_edition(edition, url='http://0.0.0.0:7860'):
|
||||
datas = json.dumps({
|
||||
"edition": edition
|
||||
})
|
||||
r = requests.post(f'{url}/cogvideox_fun/update_edition', data=datas, timeout=1500)
|
||||
data = r.content.decode('utf-8')
|
||||
return data
|
||||
|
||||
def post_infer(generation_method, length_slider, url='http://127.0.0.1:7860'):
|
||||
datas = json.dumps({
|
||||
"base_model_path": "none",
|
||||
"motion_module_path": "none",
|
||||
"lora_model_path": "none",
|
||||
"lora_alpha_slider": 0.55,
|
||||
"prompt_textbox": "This video shows Mount saint helens, washington - the stunning scenery of a rocky mountains during golden hours - wide shot. A soaring drone footage captures the majestic beauty of a coastal cliff, its red and yellow stratified rock faces rich in color and against the vibrant turquoise of the sea.",
|
||||
"negative_prompt_textbox": "Strange motion trajectory, a poor composition and deformed video, worst quality, normal quality, low quality, low resolution, duplicate and ugly, strange body structure, long and strange neck, bad teeth, bad eyes, bad limbs, bad hands, rotating camera, blurry camera, shaking camera",
|
||||
"sampler_dropdown": "Euler",
|
||||
"sample_step_slider": 30,
|
||||
"width_slider": 672,
|
||||
"height_slider": 384,
|
||||
"generation_method": "Video Generation",
|
||||
"length_slider": length_slider,
|
||||
"cfg_scale_slider": 6,
|
||||
"seed_textbox": 43,
|
||||
})
|
||||
r = requests.post(f'{url}/cogvideox_fun/infer_forward', data=datas, timeout=1500)
|
||||
data = r.content.decode('utf-8')
|
||||
return data
|
||||
|
||||
if __name__ == '__main__':
|
||||
# initiate time
|
||||
now_date = datetime.now()
|
||||
time_start = time.time()
|
||||
|
||||
# -------------------------- #
|
||||
# Step 1: update edition
|
||||
# -------------------------- #
|
||||
edition = "v3"
|
||||
outputs = post_update_edition(edition)
|
||||
print('Output update edition: ', outputs)
|
||||
|
||||
# -------------------------- #
|
||||
# Step 2: update edition
|
||||
# -------------------------- #
|
||||
diffusion_transformer_path = "models/Diffusion_Transformer/cogvideox_funV3-XL-2-512x512"
|
||||
outputs = post_diffusion_transformer(diffusion_transformer_path)
|
||||
print('Output update edition: ', outputs)
|
||||
|
||||
# -------------------------- #
|
||||
# Step 3: infer
|
||||
# -------------------------- #
|
||||
# "Video Generation" and "Image Generation"
|
||||
generation_method = "Video Generation"
|
||||
length_slider = 72
|
||||
outputs = post_infer(generation_method, length_slider)
|
||||
|
||||
# Get decoded data
|
||||
outputs = json.loads(outputs)
|
||||
base64_encoding = outputs["base64_encoding"]
|
||||
decoded_data = base64.b64decode(base64_encoding)
|
||||
|
||||
is_image = True if generation_method == "Image Generation" else False
|
||||
if is_image or length_slider == 1:
|
||||
file_path = "1.png"
|
||||
else:
|
||||
file_path = "1.mp4"
|
||||
with open(file_path, "wb") as file:
|
||||
file.write(decoded_data)
|
||||
|
||||
# End of record time
|
||||
# The calculated time difference is the execution time of the program, expressed in seconds / s
|
||||
time_end = time.time()
|
||||
time_sum = (time_end - time_start) % 60
|
||||
print('# --------------------------------------------------------- #')
|
||||
print(f'# Total expenditure: {time_sum}s')
|
||||
print('# --------------------------------------------------------- #')
|
||||
@@ -1,76 +0,0 @@
|
||||
import json
|
||||
import os
|
||||
import random
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchvision.transforms as transforms
|
||||
from PIL import Image
|
||||
from torch.utils.data.dataset import Dataset
|
||||
|
||||
|
||||
class CC15M(Dataset):
|
||||
def __init__(
|
||||
self,
|
||||
json_path,
|
||||
video_folder=None,
|
||||
resolution=512,
|
||||
enable_bucket=False,
|
||||
):
|
||||
print(f"loading annotations from {json_path} ...")
|
||||
self.dataset = json.load(open(json_path, 'r'))
|
||||
self.length = len(self.dataset)
|
||||
print(f"data scale: {self.length}")
|
||||
|
||||
self.enable_bucket = enable_bucket
|
||||
self.video_folder = video_folder
|
||||
|
||||
resolution = tuple(resolution) if not isinstance(resolution, int) else (resolution, resolution)
|
||||
self.pixel_transforms = transforms.Compose([
|
||||
transforms.Resize(resolution[0]),
|
||||
transforms.CenterCrop(resolution),
|
||||
transforms.ToTensor(),
|
||||
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
|
||||
])
|
||||
|
||||
def get_batch(self, idx):
|
||||
video_dict = self.dataset[idx]
|
||||
video_id, name = video_dict['file_path'], video_dict['text']
|
||||
|
||||
if self.video_folder is None:
|
||||
video_dir = video_id
|
||||
else:
|
||||
video_dir = os.path.join(self.video_folder, video_id)
|
||||
|
||||
pixel_values = Image.open(video_dir).convert("RGB")
|
||||
return pixel_values, name
|
||||
|
||||
def __len__(self):
|
||||
return self.length
|
||||
|
||||
def __getitem__(self, idx):
|
||||
while True:
|
||||
try:
|
||||
pixel_values, name = self.get_batch(idx)
|
||||
break
|
||||
except Exception as e:
|
||||
print(e)
|
||||
idx = random.randint(0, self.length-1)
|
||||
|
||||
if not self.enable_bucket:
|
||||
pixel_values = self.pixel_transforms(pixel_values)
|
||||
else:
|
||||
pixel_values = np.array(pixel_values)
|
||||
|
||||
sample = dict(pixel_values=pixel_values, text=name)
|
||||
return sample
|
||||
|
||||
if __name__ == "__main__":
|
||||
dataset = CC15M(
|
||||
csv_path="/mnt_wg/zhoumo.xjq/CCUtils/cc15m_add_index.json",
|
||||
resolution=512,
|
||||
)
|
||||
|
||||
dataloader = torch.utils.data.DataLoader(dataset, batch_size=4, num_workers=0,)
|
||||
for idx, batch in enumerate(dataloader):
|
||||
print(batch["pixel_values"].shape, len(batch["text"]))
|
||||
@@ -1,324 +0,0 @@
|
||||
import csv
|
||||
import io
|
||||
import json
|
||||
import math
|
||||
import os
|
||||
import random
|
||||
from threading import Thread
|
||||
|
||||
import albumentations
|
||||
import cv2
|
||||
import gc
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchvision.transforms as transforms
|
||||
|
||||
from func_timeout import func_timeout, FunctionTimedOut
|
||||
from decord import VideoReader
|
||||
from PIL import Image
|
||||
from torch.utils.data import BatchSampler, Sampler
|
||||
from torch.utils.data.dataset import Dataset
|
||||
from contextlib import contextmanager
|
||||
|
||||
VIDEO_READER_TIMEOUT = 20
|
||||
|
||||
def get_random_mask(shape):
|
||||
f, c, h, w = shape
|
||||
|
||||
if f != 1:
|
||||
mask_index = np.random.choice([0, 1, 2, 3, 4], p = [0.05, 0.3, 0.3, 0.3, 0.05]) # np.random.randint(0, 5)
|
||||
else:
|
||||
mask_index = np.random.choice([0, 1], p = [0.2, 0.8]) # np.random.randint(0, 2)
|
||||
mask = torch.zeros((f, 1, h, w), dtype=torch.uint8)
|
||||
|
||||
if mask_index == 0:
|
||||
center_x = torch.randint(0, w, (1,)).item()
|
||||
center_y = torch.randint(0, h, (1,)).item()
|
||||
block_size_x = torch.randint(w // 4, w // 4 * 3, (1,)).item() # 方块的宽度范围
|
||||
block_size_y = torch.randint(h // 4, h // 4 * 3, (1,)).item() # 方块的高度范围
|
||||
|
||||
start_x = max(center_x - block_size_x // 2, 0)
|
||||
end_x = min(center_x + block_size_x // 2, w)
|
||||
start_y = max(center_y - block_size_y // 2, 0)
|
||||
end_y = min(center_y + block_size_y // 2, h)
|
||||
mask[:, :, start_y:end_y, start_x:end_x] = 1
|
||||
elif mask_index == 1:
|
||||
mask[:, :, :, :] = 1
|
||||
elif mask_index == 2:
|
||||
mask_frame_index = np.random.randint(1, 5)
|
||||
mask[mask_frame_index:, :, :, :] = 1
|
||||
elif mask_index == 3:
|
||||
mask_frame_index = np.random.randint(1, 5)
|
||||
mask[mask_frame_index:-mask_frame_index, :, :, :] = 1
|
||||
elif mask_index == 4:
|
||||
center_x = torch.randint(0, w, (1,)).item()
|
||||
center_y = torch.randint(0, h, (1,)).item()
|
||||
block_size_x = torch.randint(w // 4, w // 4 * 3, (1,)).item() # 方块的宽度范围
|
||||
block_size_y = torch.randint(h // 4, h // 4 * 3, (1,)).item() # 方块的高度范围
|
||||
|
||||
start_x = max(center_x - block_size_x // 2, 0)
|
||||
end_x = min(center_x + block_size_x // 2, w)
|
||||
start_y = max(center_y - block_size_y // 2, 0)
|
||||
end_y = min(center_y + block_size_y // 2, h)
|
||||
|
||||
mask_frame_before = np.random.randint(0, f // 2)
|
||||
mask_frame_after = np.random.randint(f // 2, f)
|
||||
mask[mask_frame_before:mask_frame_after, :, start_y:end_y, start_x:end_x] = 1
|
||||
else:
|
||||
raise ValueError(f"The mask_index {mask_index} is not define")
|
||||
return mask
|
||||
|
||||
class ImageVideoSampler(BatchSampler):
|
||||
"""A sampler wrapper for grouping images with similar aspect ratio into a same batch.
|
||||
|
||||
Args:
|
||||
sampler (Sampler): Base sampler.
|
||||
dataset (Dataset): Dataset providing data information.
|
||||
batch_size (int): Size of mini-batch.
|
||||
drop_last (bool): If ``True``, the sampler will drop the last batch if
|
||||
its size would be less than ``batch_size``.
|
||||
aspect_ratios (dict): The predefined aspect ratios.
|
||||
"""
|
||||
|
||||
def __init__(self,
|
||||
sampler: Sampler,
|
||||
dataset: Dataset,
|
||||
batch_size: int,
|
||||
drop_last: bool = False
|
||||
) -> None:
|
||||
if not isinstance(sampler, Sampler):
|
||||
raise TypeError('sampler should be an instance of ``Sampler``, '
|
||||
f'but got {sampler}')
|
||||
if not isinstance(batch_size, int) or batch_size <= 0:
|
||||
raise ValueError('batch_size should be a positive integer value, '
|
||||
f'but got batch_size={batch_size}')
|
||||
self.sampler = sampler
|
||||
self.dataset = dataset
|
||||
self.batch_size = batch_size
|
||||
self.drop_last = drop_last
|
||||
|
||||
# buckets for each aspect ratio
|
||||
self.bucket = {'image':[], 'video':[]}
|
||||
|
||||
def __iter__(self):
|
||||
for idx in self.sampler:
|
||||
content_type = self.dataset.dataset[idx].get('type', 'image')
|
||||
self.bucket[content_type].append(idx)
|
||||
|
||||
# yield a batch of indices in the same aspect ratio group
|
||||
if len(self.bucket['video']) == self.batch_size:
|
||||
bucket = self.bucket['video']
|
||||
yield bucket[:]
|
||||
del bucket[:]
|
||||
elif len(self.bucket['image']) == self.batch_size:
|
||||
bucket = self.bucket['image']
|
||||
yield bucket[:]
|
||||
del bucket[:]
|
||||
|
||||
@contextmanager
|
||||
def VideoReader_contextmanager(*args, **kwargs):
|
||||
vr = VideoReader(*args, **kwargs)
|
||||
try:
|
||||
yield vr
|
||||
finally:
|
||||
del vr
|
||||
gc.collect()
|
||||
|
||||
def get_video_reader_batch(video_reader, batch_index):
|
||||
frames = video_reader.get_batch(batch_index).asnumpy()
|
||||
return frames
|
||||
|
||||
def resize_frame(frame, target_short_side):
|
||||
h, w, _ = frame.shape
|
||||
if h < w:
|
||||
if target_short_side > h:
|
||||
return frame
|
||||
new_h = target_short_side
|
||||
new_w = int(target_short_side * w / h)
|
||||
else:
|
||||
if target_short_side > w:
|
||||
return frame
|
||||
new_w = target_short_side
|
||||
new_h = int(target_short_side * h / w)
|
||||
|
||||
resized_frame = cv2.resize(frame, (new_w, new_h))
|
||||
return resized_frame
|
||||
|
||||
class ImageVideoDataset(Dataset):
|
||||
def __init__(
|
||||
self,
|
||||
ann_path, data_root=None,
|
||||
video_sample_size=512, video_sample_stride=4, video_sample_n_frames=16,
|
||||
image_sample_size=512,
|
||||
video_repeat=0,
|
||||
text_drop_ratio=-1,
|
||||
enable_bucket=False,
|
||||
video_length_drop_start=0.1,
|
||||
video_length_drop_end=0.9,
|
||||
enable_inpaint=False,
|
||||
):
|
||||
# Loading annotations from files
|
||||
print(f"loading annotations from {ann_path} ...")
|
||||
if ann_path.endswith('.csv'):
|
||||
with open(ann_path, 'r') as csvfile:
|
||||
dataset = list(csv.DictReader(csvfile))
|
||||
elif ann_path.endswith('.json'):
|
||||
dataset = json.load(open(ann_path))
|
||||
|
||||
self.data_root = data_root
|
||||
|
||||
# It's used to balance num of images and videos.
|
||||
self.dataset = []
|
||||
for data in dataset:
|
||||
if data.get('type', 'image') != 'video':
|
||||
self.dataset.append(data)
|
||||
if video_repeat > 0:
|
||||
for _ in range(video_repeat):
|
||||
for data in dataset:
|
||||
if data.get('type', 'image') == 'video':
|
||||
self.dataset.append(data)
|
||||
del dataset
|
||||
|
||||
self.length = len(self.dataset)
|
||||
print(f"data scale: {self.length}")
|
||||
# TODO: enable bucket training
|
||||
self.enable_bucket = enable_bucket
|
||||
self.text_drop_ratio = text_drop_ratio
|
||||
self.enable_inpaint = enable_inpaint
|
||||
|
||||
self.video_length_drop_start = video_length_drop_start
|
||||
self.video_length_drop_end = video_length_drop_end
|
||||
|
||||
# Video params
|
||||
self.video_sample_stride = video_sample_stride
|
||||
self.video_sample_n_frames = video_sample_n_frames
|
||||
self.video_sample_size = tuple(video_sample_size) if not isinstance(video_sample_size, int) else (video_sample_size, video_sample_size)
|
||||
self.video_transforms = transforms.Compose(
|
||||
[
|
||||
transforms.Resize(min(self.video_sample_size)),
|
||||
transforms.CenterCrop(self.video_sample_size),
|
||||
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
|
||||
]
|
||||
)
|
||||
|
||||
# Image params
|
||||
self.image_sample_size = tuple(image_sample_size) if not isinstance(image_sample_size, int) else (image_sample_size, image_sample_size)
|
||||
self.image_transforms = transforms.Compose([
|
||||
transforms.Resize(min(self.image_sample_size)),
|
||||
transforms.CenterCrop(self.image_sample_size),
|
||||
transforms.ToTensor(),
|
||||
transforms.Normalize([0.5, 0.5, 0.5],[0.5, 0.5, 0.5])
|
||||
])
|
||||
|
||||
self.larger_side_of_image_and_video = max(min(self.image_sample_size), min(self.video_sample_size))
|
||||
|
||||
def get_batch(self, idx):
|
||||
data_info = self.dataset[idx % len(self.dataset)]
|
||||
|
||||
if data_info.get('type', 'image')=='video':
|
||||
video_id, text = data_info['file_path'], data_info['text']
|
||||
|
||||
if self.data_root is None:
|
||||
video_dir = video_id
|
||||
else:
|
||||
video_dir = os.path.join(self.data_root, video_id)
|
||||
|
||||
with VideoReader_contextmanager(video_dir, num_threads=2) as video_reader:
|
||||
min_sample_n_frames = min(
|
||||
self.video_sample_n_frames,
|
||||
int(len(video_reader) * (self.video_length_drop_end - self.video_length_drop_start) // self.video_sample_stride)
|
||||
)
|
||||
if min_sample_n_frames == 0:
|
||||
raise ValueError(f"No Frames in video.")
|
||||
|
||||
video_length = int(self.video_length_drop_end * len(video_reader))
|
||||
clip_length = min(video_length, (min_sample_n_frames - 1) * self.video_sample_stride + 1)
|
||||
start_idx = random.randint(int(self.video_length_drop_start * video_length), video_length - clip_length) if video_length != clip_length else 0
|
||||
batch_index = np.linspace(start_idx, start_idx + clip_length - 1, min_sample_n_frames, dtype=int)
|
||||
|
||||
try:
|
||||
sample_args = (video_reader, batch_index)
|
||||
pixel_values = func_timeout(
|
||||
VIDEO_READER_TIMEOUT, get_video_reader_batch, args=sample_args
|
||||
)
|
||||
resized_frames = []
|
||||
for i in range(len(pixel_values)):
|
||||
frame = pixel_values[i]
|
||||
resized_frame = resize_frame(frame, self.larger_side_of_image_and_video)
|
||||
resized_frames.append(resized_frame)
|
||||
pixel_values = np.array(resized_frames)
|
||||
except FunctionTimedOut:
|
||||
raise ValueError(f"Read {idx} timeout.")
|
||||
except Exception as e:
|
||||
raise ValueError(f"Failed to extract frames from video. Error is {e}.")
|
||||
|
||||
if not self.enable_bucket:
|
||||
pixel_values = torch.from_numpy(pixel_values).permute(0, 3, 1, 2).contiguous()
|
||||
pixel_values = pixel_values / 255.
|
||||
del video_reader
|
||||
else:
|
||||
pixel_values = pixel_values
|
||||
|
||||
if not self.enable_bucket:
|
||||
pixel_values = self.video_transforms(pixel_values)
|
||||
|
||||
# Random use no text generation
|
||||
if random.random() < self.text_drop_ratio:
|
||||
text = ''
|
||||
return pixel_values, text, 'video'
|
||||
else:
|
||||
image_path, text = data_info['file_path'], data_info['text']
|
||||
if self.data_root is not None:
|
||||
image_path = os.path.join(self.data_root, image_path)
|
||||
image = Image.open(image_path).convert('RGB')
|
||||
if not self.enable_bucket:
|
||||
image = self.image_transforms(image).unsqueeze(0)
|
||||
else:
|
||||
image = np.expand_dims(np.array(image), 0)
|
||||
if random.random() < self.text_drop_ratio:
|
||||
text = ''
|
||||
return image, text, 'image'
|
||||
|
||||
def __len__(self):
|
||||
return self.length
|
||||
|
||||
def __getitem__(self, idx):
|
||||
data_info = self.dataset[idx % len(self.dataset)]
|
||||
data_type = data_info.get('type', 'image')
|
||||
while True:
|
||||
sample = {}
|
||||
try:
|
||||
data_info_local = self.dataset[idx % len(self.dataset)]
|
||||
data_type_local = data_info_local.get('type', 'image')
|
||||
if data_type_local != data_type:
|
||||
raise ValueError("data_type_local != data_type")
|
||||
|
||||
pixel_values, name, data_type = self.get_batch(idx)
|
||||
sample["pixel_values"] = pixel_values
|
||||
sample["text"] = name
|
||||
sample["data_type"] = data_type
|
||||
sample["idx"] = idx
|
||||
|
||||
if len(sample) > 0:
|
||||
break
|
||||
except Exception as e:
|
||||
print(e, self.dataset[idx % len(self.dataset)])
|
||||
idx = random.randint(0, self.length-1)
|
||||
|
||||
if self.enable_inpaint and not self.enable_bucket:
|
||||
mask = get_random_mask(pixel_values.size())
|
||||
mask_pixel_values = pixel_values * (1 - mask) + torch.ones_like(pixel_values) * -1 * mask
|
||||
sample["mask_pixel_values"] = mask_pixel_values
|
||||
sample["mask"] = mask
|
||||
|
||||
clip_pixel_values = sample["pixel_values"][0].permute(1, 2, 0).contiguous()
|
||||
clip_pixel_values = (clip_pixel_values * 0.5 + 0.5) * 255
|
||||
sample["clip_pixel_values"] = clip_pixel_values
|
||||
|
||||
ref_pixel_values = sample["pixel_values"][0].unsqueeze(0)
|
||||
if (mask == 1).all():
|
||||
ref_pixel_values = torch.ones_like(ref_pixel_values) * -1
|
||||
sample["ref_pixel_values"] = ref_pixel_values
|
||||
|
||||
return sample
|
||||
|
||||
@@ -1,262 +0,0 @@
|
||||
import csv
|
||||
import gc
|
||||
import io
|
||||
import json
|
||||
import math
|
||||
import os
|
||||
import random
|
||||
from contextlib import contextmanager
|
||||
from threading import Thread
|
||||
|
||||
import albumentations
|
||||
import cv2
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchvision.transforms as transforms
|
||||
from decord import VideoReader
|
||||
from einops import rearrange
|
||||
from func_timeout import FunctionTimedOut, func_timeout
|
||||
from PIL import Image
|
||||
from torch.utils.data import BatchSampler, Sampler
|
||||
from torch.utils.data.dataset import Dataset
|
||||
|
||||
VIDEO_READER_TIMEOUT = 20
|
||||
|
||||
def get_random_mask(shape):
|
||||
f, c, h, w = shape
|
||||
|
||||
mask_index = np.random.randint(0, 4)
|
||||
mask = torch.zeros((f, 1, h, w), dtype=torch.uint8)
|
||||
if mask_index == 0:
|
||||
mask[1:, :, :, :] = 1
|
||||
elif mask_index == 1:
|
||||
mask_frame_index = 1
|
||||
mask[mask_frame_index:-mask_frame_index, :, :, :] = 1
|
||||
elif mask_index == 2:
|
||||
center_x = torch.randint(0, w, (1,)).item()
|
||||
center_y = torch.randint(0, h, (1,)).item()
|
||||
block_size_x = torch.randint(w // 4, w // 4 * 3, (1,)).item() # 方块的宽度范围
|
||||
block_size_y = torch.randint(h // 4, h // 4 * 3, (1,)).item() # 方块的高度范围
|
||||
|
||||
start_x = max(center_x - block_size_x // 2, 0)
|
||||
end_x = min(center_x + block_size_x // 2, w)
|
||||
start_y = max(center_y - block_size_y // 2, 0)
|
||||
end_y = min(center_y + block_size_y // 2, h)
|
||||
mask[:, :, start_y:end_y, start_x:end_x] = 1
|
||||
elif mask_index == 3:
|
||||
center_x = torch.randint(0, w, (1,)).item()
|
||||
center_y = torch.randint(0, h, (1,)).item()
|
||||
block_size_x = torch.randint(w // 4, w // 4 * 3, (1,)).item() # 方块的宽度范围
|
||||
block_size_y = torch.randint(h // 4, h // 4 * 3, (1,)).item() # 方块的高度范围
|
||||
|
||||
start_x = max(center_x - block_size_x // 2, 0)
|
||||
end_x = min(center_x + block_size_x // 2, w)
|
||||
start_y = max(center_y - block_size_y // 2, 0)
|
||||
end_y = min(center_y + block_size_y // 2, h)
|
||||
|
||||
mask_frame_before = np.random.randint(0, f // 2)
|
||||
mask_frame_after = np.random.randint(f // 2, f)
|
||||
mask[mask_frame_before:mask_frame_after, :, start_y:end_y, start_x:end_x] = 1
|
||||
else:
|
||||
raise ValueError(f"The mask_index {mask_index} is not define")
|
||||
return mask
|
||||
|
||||
|
||||
@contextmanager
|
||||
def VideoReader_contextmanager(*args, **kwargs):
|
||||
vr = VideoReader(*args, **kwargs)
|
||||
try:
|
||||
yield vr
|
||||
finally:
|
||||
del vr
|
||||
gc.collect()
|
||||
|
||||
|
||||
def get_video_reader_batch(video_reader, batch_index):
|
||||
frames = video_reader.get_batch(batch_index).asnumpy()
|
||||
return frames
|
||||
|
||||
|
||||
class WebVid10M(Dataset):
|
||||
def __init__(
|
||||
self,
|
||||
csv_path, video_folder,
|
||||
sample_size=256, sample_stride=4, sample_n_frames=16,
|
||||
enable_bucket=False, enable_inpaint=False, is_image=False,
|
||||
):
|
||||
print(f"loading annotations from {csv_path} ...")
|
||||
with open(csv_path, 'r') as csvfile:
|
||||
self.dataset = list(csv.DictReader(csvfile))
|
||||
self.length = len(self.dataset)
|
||||
print(f"data scale: {self.length}")
|
||||
|
||||
self.video_folder = video_folder
|
||||
self.sample_stride = sample_stride
|
||||
self.sample_n_frames = sample_n_frames
|
||||
self.enable_bucket = enable_bucket
|
||||
self.enable_inpaint = enable_inpaint
|
||||
self.is_image = is_image
|
||||
|
||||
sample_size = tuple(sample_size) if not isinstance(sample_size, int) else (sample_size, sample_size)
|
||||
self.pixel_transforms = transforms.Compose([
|
||||
transforms.Resize(sample_size[0]),
|
||||
transforms.CenterCrop(sample_size),
|
||||
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
|
||||
])
|
||||
|
||||
def get_batch(self, idx):
|
||||
video_dict = self.dataset[idx]
|
||||
videoid, name, page_dir = video_dict['videoid'], video_dict['name'], video_dict['page_dir']
|
||||
|
||||
video_dir = os.path.join(self.video_folder, f"{videoid}.mp4")
|
||||
video_reader = VideoReader(video_dir)
|
||||
video_length = len(video_reader)
|
||||
|
||||
if not self.is_image:
|
||||
clip_length = min(video_length, (self.sample_n_frames - 1) * self.sample_stride + 1)
|
||||
start_idx = random.randint(0, video_length - clip_length)
|
||||
batch_index = np.linspace(start_idx, start_idx + clip_length - 1, self.sample_n_frames, dtype=int)
|
||||
else:
|
||||
batch_index = [random.randint(0, video_length - 1)]
|
||||
|
||||
if not self.enable_bucket:
|
||||
pixel_values = torch.from_numpy(video_reader.get_batch(batch_index).asnumpy()).permute(0, 3, 1, 2).contiguous()
|
||||
pixel_values = pixel_values / 255.
|
||||
del video_reader
|
||||
else:
|
||||
pixel_values = video_reader.get_batch(batch_index).asnumpy()
|
||||
|
||||
if self.is_image:
|
||||
pixel_values = pixel_values[0]
|
||||
return pixel_values, name
|
||||
|
||||
def __len__(self):
|
||||
return self.length
|
||||
|
||||
def __getitem__(self, idx):
|
||||
while True:
|
||||
try:
|
||||
pixel_values, name = self.get_batch(idx)
|
||||
break
|
||||
|
||||
except Exception as e:
|
||||
print("Error info:", e)
|
||||
idx = random.randint(0, self.length-1)
|
||||
|
||||
if not self.enable_bucket:
|
||||
pixel_values = self.pixel_transforms(pixel_values)
|
||||
if self.enable_inpaint:
|
||||
mask = get_random_mask(pixel_values.size())
|
||||
mask_pixel_values = pixel_values * (1 - mask) + torch.ones_like(pixel_values) * -1 * mask
|
||||
sample = dict(pixel_values=pixel_values, mask_pixel_values=mask_pixel_values, mask=mask, text=name)
|
||||
else:
|
||||
sample = dict(pixel_values=pixel_values, text=name)
|
||||
return sample
|
||||
|
||||
|
||||
class VideoDataset(Dataset):
|
||||
def __init__(
|
||||
self,
|
||||
json_path, video_folder=None,
|
||||
sample_size=256, sample_stride=4, sample_n_frames=16,
|
||||
enable_bucket=False, enable_inpaint=False
|
||||
):
|
||||
print(f"loading annotations from {json_path} ...")
|
||||
self.dataset = json.load(open(json_path, 'r'))
|
||||
self.length = len(self.dataset)
|
||||
print(f"data scale: {self.length}")
|
||||
|
||||
self.video_folder = video_folder
|
||||
self.sample_stride = sample_stride
|
||||
self.sample_n_frames = sample_n_frames
|
||||
self.enable_bucket = enable_bucket
|
||||
self.enable_inpaint = enable_inpaint
|
||||
|
||||
sample_size = tuple(sample_size) if not isinstance(sample_size, int) else (sample_size, sample_size)
|
||||
self.pixel_transforms = transforms.Compose(
|
||||
[
|
||||
transforms.Resize(sample_size[0]),
|
||||
transforms.CenterCrop(sample_size),
|
||||
transforms.Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5], inplace=True),
|
||||
]
|
||||
)
|
||||
|
||||
def get_batch(self, idx):
|
||||
video_dict = self.dataset[idx]
|
||||
video_id, name = video_dict['file_path'], video_dict['text']
|
||||
|
||||
if self.video_folder is None:
|
||||
video_dir = video_id
|
||||
else:
|
||||
video_dir = os.path.join(self.video_folder, video_id)
|
||||
|
||||
with VideoReader_contextmanager(video_dir, num_threads=2) as video_reader:
|
||||
video_length = len(video_reader)
|
||||
|
||||
clip_length = min(video_length, (self.sample_n_frames - 1) * self.sample_stride + 1)
|
||||
start_idx = random.randint(0, video_length - clip_length)
|
||||
batch_index = np.linspace(start_idx, start_idx + clip_length - 1, self.sample_n_frames, dtype=int)
|
||||
|
||||
try:
|
||||
sample_args = (video_reader, batch_index)
|
||||
pixel_values = func_timeout(
|
||||
VIDEO_READER_TIMEOUT, get_video_reader_batch, args=sample_args
|
||||
)
|
||||
except FunctionTimedOut:
|
||||
raise ValueError(f"Read {idx} timeout.")
|
||||
except Exception as e:
|
||||
raise ValueError(f"Failed to extract frames from video. Error is {e}.")
|
||||
|
||||
if not self.enable_bucket:
|
||||
pixel_values = torch.from_numpy(pixel_values).permute(0, 3, 1, 2).contiguous()
|
||||
pixel_values = pixel_values / 255.
|
||||
del video_reader
|
||||
else:
|
||||
pixel_values = pixel_values
|
||||
|
||||
return pixel_values, name
|
||||
|
||||
def __len__(self):
|
||||
return self.length
|
||||
|
||||
def __getitem__(self, idx):
|
||||
while True:
|
||||
try:
|
||||
pixel_values, name = self.get_batch(idx)
|
||||
break
|
||||
|
||||
except Exception as e:
|
||||
print("Error info:", e)
|
||||
idx = random.randint(0, self.length-1)
|
||||
|
||||
if not self.enable_bucket:
|
||||
pixel_values = self.pixel_transforms(pixel_values)
|
||||
if self.enable_inpaint:
|
||||
mask = get_random_mask(pixel_values.size())
|
||||
mask_pixel_values = pixel_values * (1 - mask) + torch.ones_like(pixel_values) * -1 * mask
|
||||
sample = dict(pixel_values=pixel_values, mask_pixel_values=mask_pixel_values, mask=mask, text=name)
|
||||
else:
|
||||
sample = dict(pixel_values=pixel_values, text=name)
|
||||
return sample
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
if 1:
|
||||
dataset = VideoDataset(
|
||||
json_path="/home/zhoumo.xjq/disk3/datasets/webvidval/results_2M_val.json",
|
||||
sample_size=256,
|
||||
sample_stride=4, sample_n_frames=16,
|
||||
)
|
||||
|
||||
if 0:
|
||||
dataset = WebVid10M(
|
||||
csv_path="/mnt/petrelfs/guoyuwei/projects/datasets/webvid/results_2M_val.csv",
|
||||
video_folder="/mnt/petrelfs/guoyuwei/projects/datasets/webvid/2M_val",
|
||||
sample_size=256,
|
||||
sample_stride=4, sample_n_frames=16,
|
||||
is_image=False,
|
||||
)
|
||||
|
||||
dataloader = torch.utils.data.DataLoader(dataset, batch_size=4, num_workers=0,)
|
||||
for idx, batch in enumerate(dataloader):
|
||||
print(batch["pixel_values"].shape, len(batch["text"]))
|
||||
@@ -1,189 +0,0 @@
|
||||
import os
|
||||
import gc
|
||||
import imageio
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchvision
|
||||
import cv2
|
||||
from einops import rearrange
|
||||
from PIL import Image
|
||||
|
||||
def get_width_and_height_from_image_and_base_resolution(image, base_resolution):
|
||||
target_pixels = int(base_resolution) * int(base_resolution)
|
||||
original_width, original_height = Image.open(image).size
|
||||
ratio = (target_pixels / (original_width * original_height)) ** 0.5
|
||||
width_slider = round(original_width * ratio)
|
||||
height_slider = round(original_height * ratio)
|
||||
return height_slider, width_slider
|
||||
|
||||
def color_transfer(sc, dc):
|
||||
"""
|
||||
Transfer color distribution from of sc, referred to dc.
|
||||
|
||||
Args:
|
||||
sc (numpy.ndarray): input image to be transfered.
|
||||
dc (numpy.ndarray): reference image
|
||||
|
||||
Returns:
|
||||
numpy.ndarray: Transferred color distribution on the sc.
|
||||
"""
|
||||
|
||||
def get_mean_and_std(img):
|
||||
x_mean, x_std = cv2.meanStdDev(img)
|
||||
x_mean = np.hstack(np.around(x_mean, 2))
|
||||
x_std = np.hstack(np.around(x_std, 2))
|
||||
return x_mean, x_std
|
||||
|
||||
sc = cv2.cvtColor(sc, cv2.COLOR_RGB2LAB)
|
||||
s_mean, s_std = get_mean_and_std(sc)
|
||||
dc = cv2.cvtColor(dc, cv2.COLOR_RGB2LAB)
|
||||
t_mean, t_std = get_mean_and_std(dc)
|
||||
img_n = ((sc - s_mean) * (t_std / s_std)) + t_mean
|
||||
np.putmask(img_n, img_n > 255, 255)
|
||||
np.putmask(img_n, img_n < 0, 0)
|
||||
dst = cv2.cvtColor(cv2.convertScaleAbs(img_n), cv2.COLOR_LAB2RGB)
|
||||
return dst
|
||||
|
||||
def save_videos_grid(videos: torch.Tensor, path: str, rescale=False, n_rows=6, fps=12, imageio_backend=True, color_transfer_post_process=False):
|
||||
videos = rearrange(videos, "b c t h w -> t b c h w")
|
||||
outputs = []
|
||||
for x in videos:
|
||||
x = torchvision.utils.make_grid(x, nrow=n_rows)
|
||||
x = x.transpose(0, 1).transpose(1, 2).squeeze(-1)
|
||||
if rescale:
|
||||
x = (x + 1.0) / 2.0 # -1,1 -> 0,1
|
||||
x = (x * 255).numpy().astype(np.uint8)
|
||||
outputs.append(Image.fromarray(x))
|
||||
|
||||
if color_transfer_post_process:
|
||||
for i in range(1, len(outputs)):
|
||||
outputs[i] = Image.fromarray(color_transfer(np.uint8(outputs[i]), np.uint8(outputs[0])))
|
||||
|
||||
os.makedirs(os.path.dirname(path), exist_ok=True)
|
||||
if imageio_backend:
|
||||
if path.endswith("mp4"):
|
||||
imageio.mimsave(path, outputs, fps=fps)
|
||||
else:
|
||||
imageio.mimsave(path, outputs, duration=(1000 * 1/fps))
|
||||
else:
|
||||
if path.endswith("mp4"):
|
||||
path = path.replace('.mp4', '.gif')
|
||||
outputs[0].save(path, format='GIF', append_images=outputs, save_all=True, duration=100, loop=0)
|
||||
|
||||
def get_image_to_video_latent(validation_image_start, validation_image_end, video_length, sample_size):
|
||||
if validation_image_start is not None and validation_image_end is not None:
|
||||
if type(validation_image_start) is str and os.path.isfile(validation_image_start):
|
||||
image_start = clip_image = Image.open(validation_image_start).convert("RGB")
|
||||
image_start = image_start.resize([sample_size[1], sample_size[0]])
|
||||
clip_image = clip_image.resize([sample_size[1], sample_size[0]])
|
||||
else:
|
||||
image_start = clip_image = validation_image_start
|
||||
image_start = [_image_start.resize([sample_size[1], sample_size[0]]) for _image_start in image_start]
|
||||
clip_image = [_clip_image.resize([sample_size[1], sample_size[0]]) for _clip_image in clip_image]
|
||||
|
||||
if type(validation_image_end) is str and os.path.isfile(validation_image_end):
|
||||
image_end = Image.open(validation_image_end).convert("RGB")
|
||||
image_end = image_end.resize([sample_size[1], sample_size[0]])
|
||||
else:
|
||||
image_end = validation_image_end
|
||||
image_end = [_image_end.resize([sample_size[1], sample_size[0]]) for _image_end in image_end]
|
||||
|
||||
if type(image_start) is list:
|
||||
clip_image = clip_image[0]
|
||||
start_video = torch.cat(
|
||||
[torch.from_numpy(np.array(_image_start)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0) for _image_start in image_start],
|
||||
dim=2
|
||||
)
|
||||
input_video = torch.tile(start_video[:, :, :1], [1, 1, video_length, 1, 1])
|
||||
input_video[:, :, :len(image_start)] = start_video
|
||||
|
||||
input_video_mask = torch.zeros_like(input_video[:, :1])
|
||||
input_video_mask[:, :, len(image_start):] = 255
|
||||
else:
|
||||
input_video = torch.tile(
|
||||
torch.from_numpy(np.array(image_start)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0),
|
||||
[1, 1, video_length, 1, 1]
|
||||
)
|
||||
input_video_mask = torch.zeros_like(input_video[:, :1])
|
||||
input_video_mask[:, :, 3:] = 255
|
||||
|
||||
if type(image_end) is list:
|
||||
image_end = [_image_end.resize(image_start[0].size if type(image_start) is list else image_start.size) for _image_end in image_end]
|
||||
end_video = torch.cat(
|
||||
[torch.from_numpy(np.array(_image_end)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0) for _image_end in image_end],
|
||||
dim=2
|
||||
)
|
||||
input_video[:, :, -len(end_video):] = end_video
|
||||
|
||||
input_video_mask[:, :, -len(image_end):] = 0
|
||||
else:
|
||||
image_end = image_end.resize(image_start[0].size if type(image_start) is list else image_start.size)
|
||||
input_video[:, :, -3:] = torch.from_numpy(np.array(image_end)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0)
|
||||
input_video_mask[:, :, -3:] = 0
|
||||
|
||||
input_video = input_video / 255
|
||||
|
||||
elif validation_image_start is not None:
|
||||
if type(validation_image_start) is str and os.path.isfile(validation_image_start):
|
||||
image_start = clip_image = Image.open(validation_image_start).convert("RGB")
|
||||
image_start = image_start.resize([sample_size[1], sample_size[0]])
|
||||
clip_image = clip_image.resize([sample_size[1], sample_size[0]])
|
||||
else:
|
||||
image_start = clip_image = validation_image_start
|
||||
image_start = [_image_start.resize([sample_size[1], sample_size[0]]) for _image_start in image_start]
|
||||
clip_image = [_clip_image.resize([sample_size[1], sample_size[0]]) for _clip_image in clip_image]
|
||||
image_end = None
|
||||
|
||||
if type(image_start) is list:
|
||||
clip_image = clip_image[0]
|
||||
start_video = torch.cat(
|
||||
[torch.from_numpy(np.array(_image_start)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0) for _image_start in image_start],
|
||||
dim=2
|
||||
)
|
||||
input_video = torch.tile(start_video[:, :, :1], [1, 1, video_length, 1, 1])
|
||||
input_video[:, :, :len(image_start)] = start_video
|
||||
input_video = input_video / 255
|
||||
|
||||
input_video_mask = torch.zeros_like(input_video[:, :1])
|
||||
input_video_mask[:, :, len(image_start):] = 255
|
||||
else:
|
||||
input_video = torch.tile(
|
||||
torch.from_numpy(np.array(image_start)).permute(2, 0, 1).unsqueeze(1).unsqueeze(0),
|
||||
[1, 1, video_length, 1, 1]
|
||||
) / 255
|
||||
input_video_mask = torch.zeros_like(input_video[:, :1])
|
||||
input_video_mask[:, :, 3:, ] = 255
|
||||
else:
|
||||
image_start = None
|
||||
image_end = None
|
||||
input_video = torch.zeros([1, 3, video_length, sample_size[0], sample_size[1]])
|
||||
input_video_mask = torch.ones([1, 1, video_length, sample_size[0], sample_size[1]]) * 255
|
||||
clip_image = None
|
||||
|
||||
del image_start
|
||||
del image_end
|
||||
gc.collect()
|
||||
|
||||
return input_video, input_video_mask, clip_image
|
||||
|
||||
def get_video_to_video_latent(input_video_path, video_length, sample_size):
|
||||
if type(input_video_path) is str:
|
||||
cap = cv2.VideoCapture(input_video_path)
|
||||
input_video = []
|
||||
while True:
|
||||
ret, frame = cap.read()
|
||||
if not ret:
|
||||
break
|
||||
frame = cv2.resize(frame, (sample_size[1], sample_size[0]))
|
||||
input_video.append(cv2.cvtColor(frame, cv2.COLOR_BGR2RGB))
|
||||
cap.release()
|
||||
else:
|
||||
input_video = input_video_path
|
||||
|
||||
input_video = torch.from_numpy(np.array(input_video))[:video_length]
|
||||
input_video = input_video.permute([3, 0, 1, 2]).unsqueeze(0) / 255
|
||||
|
||||
input_video_mask = torch.zeros_like(input_video[:, :1])
|
||||
input_video_mask[:, :, :] = 255
|
||||
|
||||
return input_video, input_video_mask, None
|
||||
@@ -1,42 +0,0 @@
|
||||
# Modified from https://github.com/NVlabs/VILA/blob/1c88211/llava/model/multimodal_encoder/siglip_encoder.py
|
||||
# 1. Support transformers >= 4.36.2.
|
||||
import torch
|
||||
import transformers
|
||||
from packaging import version
|
||||
from transformers import AutoConfig, AutoModel, PretrainedConfig
|
||||
|
||||
from llava.model.multimodal_encoder.vision_encoder import VisionTower, VisionTowerS2
|
||||
|
||||
if version.parse(transformers.__version__) > version.parse("4.36.2"):
|
||||
from transformers import SiglipImageProcessor, SiglipVisionConfig, SiglipVisionModel
|
||||
else:
|
||||
from .siglip import SiglipImageProcessor, SiglipVisionConfig, SiglipVisionModel
|
||||
|
||||
|
||||
class SiglipVisionTower(VisionTower):
|
||||
def __init__(self, model_name_or_path: str, config: PretrainedConfig, state_dict=None):
|
||||
super().__init__(model_name_or_path, config)
|
||||
self.image_processor = SiglipImageProcessor.from_pretrained(model_name_or_path)
|
||||
self.vision_tower = SiglipVisionModel.from_pretrained(
|
||||
# TODO(ligeng): why pass config here leading to errors?
|
||||
model_name_or_path, torch_dtype=eval(config.model_dtype), state_dict=state_dict
|
||||
)
|
||||
self.is_loaded = True
|
||||
|
||||
|
||||
class SiglipVisionTowerS2(VisionTowerS2):
|
||||
def __init__(self, model_name_or_path: str, config: PretrainedConfig):
|
||||
super().__init__(model_name_or_path, config)
|
||||
self.image_processor = SiglipImageProcessor.from_pretrained(model_name_or_path)
|
||||
self.vision_tower = SiglipVisionModel.from_pretrained(
|
||||
model_name_or_path, torch_dtype=eval(config.model_dtype)
|
||||
)
|
||||
|
||||
# Make sure it crops/resizes the image to the largest scale in self.scales to maintain high-res information
|
||||
self.image_processor.size['height'] = self.image_processor.size['width'] = self.scales[-1]
|
||||
|
||||
self.is_loaded = True
|
||||
|
||||
if version.parse(transformers.__version__) <= version.parse("4.36.2"):
|
||||
AutoConfig.register("siglip_vision_model", SiglipVisionConfig)
|
||||
AutoModel.register(SiglipVisionConfig, SiglipVisionModel)
|
||||
@@ -1,41 +0,0 @@
|
||||
META_FILE_PATH="datasets/panda_70m/videos_clips/data/meta_file_info.jsonl"
|
||||
VIDEO_FOLDER="datasets/panda_70m/videos_clips/data/"
|
||||
VIDEO_QUALITY_SAVED_PATH="datasets/panda_70m/videos_clips/meta_quality_info_siglip.jsonl"
|
||||
MIN_ASETHETIC_SCORE_SIGLIP=4.0
|
||||
TEXT_SAVED_PATH="datasets/panda_70m/videos_clips/meta_text_info.jsonl"
|
||||
MIN_TEXT_SCORE=0.02
|
||||
MOTION_SAVED_PATH="datasets/panda_70m/videos_clips/meta_motion_info.jsonl"
|
||||
|
||||
python -m utils.get_meta_file \
|
||||
--video_folder $VIDEO_FOLDER \
|
||||
--saved_path $META_FILE_PATH
|
||||
|
||||
# Get the asethetic score (SigLIP) of all videos
|
||||
accelerate launch compute_video_quality.py \
|
||||
--video_metadata_path $META_FILE_PATH \
|
||||
--video_folder $VIDEO_FOLDER \
|
||||
--metrics "AestheticScoreSigLIP" \
|
||||
--frame_sample_method uniform \
|
||||
--num_sampled_frames 4 \
|
||||
--saved_freq 10 \
|
||||
--saved_path $VIDEO_QUALITY_SAVED_PATH \
|
||||
--batch_size 4
|
||||
|
||||
# Get the text score of all videos filtered by the video quality score.
|
||||
accelerate launch compute_text_score.py \
|
||||
--video_metadata_path $META_FILE_PATH \
|
||||
--video_folder $VIDEO_FOLDER \
|
||||
--saved_freq 10 \
|
||||
--saved_path $TEXT_SAVED_PATH \
|
||||
--asethetic_score_siglip_metadata_path $VIDEO_QUALITY_SAVED_PATH \
|
||||
--min_asethetic_score_siglip $MIN_ASETHETIC_SCORE_SIGLIP
|
||||
|
||||
# Get the motion score of all videos filtered by the video quality score and text score.
|
||||
python compute_motion_score.py \
|
||||
--video_metadata_path $META_FILE_PATH \
|
||||
--video_folder $VIDEO_FOLDER \
|
||||
--saved_freq 10 \
|
||||
--saved_path $MOTION_SAVED_PATH \
|
||||
--n_jobs 8 \
|
||||
--text_score_metadata_path $TEXT_SAVED_PATH \
|
||||
--min_text_score $MIN_TEXT_SCORE
|
||||
@@ -1,52 +0,0 @@
|
||||
META_FILE_PATH="datasets/panda_70m/videos_clips/data/meta_file_info.jsonl"
|
||||
VIDEO_FOLDER="datasets/panda_70m/videos_clips/data/"
|
||||
MOTION_SAVED_PATH="datasets/panda_70m/videos_clips/meta_motion_info.jsonl"
|
||||
MIN_MOTION_SCORE=2
|
||||
VIDEO_CAPTION_SAVED_PATH="datasets/panda_70m/meta_caption_info_vila_8b.jsonl"
|
||||
REWRITTEN_VIDEO_CAPTION_SAVED_PATH="datasets/panda_70m/meta_caption_info_vila_8b_rewritten.jsonl"
|
||||
VIDEOCLIPXL_SCORE_SAVED_PATH="datasets/panda_70m/meta_caption_info_vila_8b_rewritten_videoclipxl.jsonl"
|
||||
MIN_VIDEOCLIPXL_SCORE=0.20
|
||||
TRAIN_SAVED_PATH="datasets/panda_70m/train_panda_70m.json"
|
||||
# Manually download Efficient-Large-Model/Llama-3-VILA1.5-8b-AWQ to VILA_MODEL_PATH.
|
||||
# Manually download meta-llama/Meta-Llama-3-8B-Instruct to REWRITE_MODEL_PATH.
|
||||
|
||||
# Use VILA1.5-AWQ to perform recaptioning.
|
||||
accelerate launch vila_video_recaptioning.py \
|
||||
--video_metadata_path ${META_FILE_PATH} \
|
||||
--video_folder ${VIDEO_FOLDER} \
|
||||
--model_path ${VILA_MODEL_PATH} \
|
||||
--precision "W4A16" \
|
||||
--saved_path $VIDEO_CAPTION_SAVED_PATH \
|
||||
--saved_freq 1 \
|
||||
--motion_score_metadata_path $MOTION_SAVED_PATH \
|
||||
--min_motion_score $MIN_MOTION_SCORE
|
||||
|
||||
# Rewrite video captions (optional).
|
||||
python caption_rewrite.py \
|
||||
--video_metadata_path $VIDEO_CAPTION_SAVED_PATH \
|
||||
--batch_size 4096 \
|
||||
--model_name $REWRITE_MODEL_PATH \
|
||||
--prompt prompt/rewrite.txt \
|
||||
--prefix '"rewritten description": ' \
|
||||
--saved_path $REWRITTEN_VIDEO_CAPTION_SAVED_PATH \
|
||||
--saved_freq 1
|
||||
|
||||
# Compute caption-video alignment (optional).
|
||||
accelerate launch compute_video_quality.py \
|
||||
--video_metadata_path $REWRITTEN_VIDEO_CAPTION_SAVED_PATH \
|
||||
--caption_column caption \
|
||||
--video_folder $VIDEO_FOLDER \
|
||||
--frame_sample_method uniform \
|
||||
--num_sampled_frames 8 \
|
||||
--metrics VideoCLIPXLScore \
|
||||
--batch_size 4 \
|
||||
--saved_path $VIDEOCLIPXL_SCORE_SAVED_PATH \
|
||||
--saved_freq 10
|
||||
|
||||
# Get the final train file.
|
||||
python filter_meta_train.py \
|
||||
--caption_metadata_path $REWRITTEN_VIDEO_CAPTION_SAVED_PATH \
|
||||
--video_folder=$VIDEO_FOLDER \
|
||||
--videoclipxl_score_metadata_path $VIDEOCLIPXL_SCORE_SAVED_PATH \
|
||||
--min_videoclipxl_score $MIN_VIDEOCLIPXL_SCORE \
|
||||
--saved_path=$TRAIN_SAVED_PATH
|
||||
@@ -1,44 +0,0 @@
|
||||
import gc
|
||||
import random
|
||||
from contextlib import contextmanager
|
||||
from typing import List, Tuple, Optional
|
||||
|
||||
import numpy as np
|
||||
from decord import VideoReader
|
||||
from PIL import Image
|
||||
|
||||
|
||||
@contextmanager
|
||||
def video_reader(*args, **kwargs):
|
||||
"""A context manager to solve the memory leak of decord.
|
||||
"""
|
||||
vr = VideoReader(*args, **kwargs)
|
||||
try:
|
||||
yield vr
|
||||
finally:
|
||||
del vr
|
||||
gc.collect()
|
||||
|
||||
|
||||
def extract_frames(
|
||||
video_path: str,
|
||||
sample_method: str = "mid",
|
||||
num_sampled_frames: int = -1,
|
||||
sample_stride: int = -1,
|
||||
**kwargs
|
||||
) -> Optional[Tuple[List[int], List[Image.Image]]]:
|
||||
with video_reader(video_path, num_threads=2, **kwargs) as vr:
|
||||
if sample_method == "mid":
|
||||
sampled_frame_idx_list = [len(vr) // 2]
|
||||
elif sample_method == "uniform":
|
||||
sampled_frame_idx_list = np.linspace(0, len(vr), num_sampled_frames, endpoint=False, dtype=int)
|
||||
elif sample_method == "random":
|
||||
clip_length = min(len(vr), (num_sampled_frames - 1) * sample_stride + 1)
|
||||
start_idx = random.randint(0, len(vr) - clip_length)
|
||||
sampled_frame_idx_list = np.linspace(start_idx, start_idx + clip_length - 1, num_sampled_frames, dtype=int)
|
||||
else:
|
||||
raise ValueError(f"The sample_method {sample_method} must be mid, uniform or random.")
|
||||
sampled_frame_list = vr.get_batch(sampled_frame_idx_list).asnumpy()
|
||||
sampled_frame_list = [Image.fromarray(frame) for frame in sampled_frame_list]
|
||||
|
||||
return list(sampled_frame_idx_list), sampled_frame_list
|
||||
@@ -1,354 +0,0 @@
|
||||
# Modified from https://github.com/mit-han-lab/llm-awq/blob/main/tinychat/vlm_demo_new.py.
|
||||
import argparse
|
||||
import os
|
||||
from pathlib import Path
|
||||
|
||||
import numpy as np
|
||||
import pandas as pd
|
||||
import torch
|
||||
from accelerate import load_checkpoint_and_dispatch, PartialState
|
||||
from accelerate.utils import gather_object
|
||||
from decord import VideoReader
|
||||
from PIL import Image
|
||||
from natsort import natsorted
|
||||
from tqdm import tqdm
|
||||
from transformers import AutoConfig, AutoTokenizer
|
||||
|
||||
import tinychat.utils.constants
|
||||
# from tinychat.models.llava_llama import LlavaLlamaForCausalLM
|
||||
from tinychat.models.vila_llama import VilaLlamaForCausalLM
|
||||
from tinychat.stream_generators.llava_stream_gen import LlavaStreamGenerator
|
||||
from tinychat.utils.conversation_utils import gen_params
|
||||
from tinychat.utils.llava_image_processing import process_images
|
||||
from tinychat.utils.prompt_templates import (
|
||||
get_image_token,
|
||||
get_prompter,
|
||||
get_stop_token_ids,
|
||||
)
|
||||
from tinychat.utils.tune import (
|
||||
device_warmup,
|
||||
tune_llava_patch_embedding,
|
||||
)
|
||||
|
||||
from utils.filter import filter
|
||||
from utils.logger import logger
|
||||
|
||||
gen_params.seed = 1
|
||||
gen_params.temp = 1.0
|
||||
gen_params.top_p = 1.0
|
||||
|
||||
|
||||
def extract_uniform_frames(video_path: str, num_sampled_frames: int = 8):
|
||||
vr = VideoReader(video_path)
|
||||
sampled_frame_idx_list = np.linspace(0, len(vr), num_sampled_frames, endpoint=False, dtype=int)
|
||||
sampled_frame_list = []
|
||||
for idx in sampled_frame_idx_list:
|
||||
sampled_frame = Image.fromarray(vr[idx].asnumpy())
|
||||
sampled_frame_list.append(sampled_frame)
|
||||
|
||||
return sampled_frame_list
|
||||
|
||||
|
||||
def stream_output(output_stream):
|
||||
for outputs in output_stream:
|
||||
output_text = outputs["text"]
|
||||
output_text = output_text.strip().split(" ")
|
||||
# print(f"output_text: {output_text}.")
|
||||
return " ".join(output_text)
|
||||
|
||||
|
||||
def skip(*args, **kwargs):
|
||||
pass
|
||||
|
||||
|
||||
def parse_args():
|
||||
parser = argparse.ArgumentParser(description="Recaption videos with VILA1.5.")
|
||||
parser.add_argument(
|
||||
"--video_metadata_path",
|
||||
type=str,
|
||||
default=None,
|
||||
help="The path to the video dataset metadata (csv/jsonl).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--video_path_column",
|
||||
type=str,
|
||||
default="video_path",
|
||||
help="The column contains the video path (an absolute path or a relative path w.r.t the video_folder).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--caption_column",
|
||||
type=str,
|
||||
default="caption",
|
||||
help="The column contains the caption.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--video_folder", type=str, default="", help="The video folder."
|
||||
)
|
||||
parser.add_argument("--input_prompt", type=str, default="<video>\\n Elaborate on the visual and narrative elements of the video in detail.")
|
||||
parser.add_argument(
|
||||
"--model_type", type=str, default="LLaMa", help="type of the model"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--model_path", type=str, default="Efficient-Large-Model/Llama-3-VILA1.5-8b-AWQ"
|
||||
)
|
||||
parser.add_argument(
|
||||
"--quant_path",
|
||||
type=str,
|
||||
default=None,
|
||||
)
|
||||
parser.add_argument(
|
||||
"--precision", type=str, default="W4A16", help="compute precision"
|
||||
)
|
||||
parser.add_argument("--num_sampled_frames", type=int, default=8)
|
||||
parser.add_argument(
|
||||
"--saved_path",
|
||||
type=str,
|
||||
required=True,
|
||||
help="The save path to the output results (csv/jsonl).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--saved_freq",
|
||||
type=int,
|
||||
default=100,
|
||||
help="The frequency to save the output results.",
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--basic_metadata_path", type=str, default=None, help="The path to the basic metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_resolution", type=float, default=0, help="The resolution threshold.")
|
||||
parser.add_argument("--min_duration", type=float, default=-1, help="The minimum duration.")
|
||||
parser.add_argument("--max_duration", type=float, default=-1, help="The maximum duration.")
|
||||
parser.add_argument(
|
||||
"--asethetic_score_metadata_path", type=str, default=None, help="The path to the video quality metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_asethetic_score", type=float, default=4.0, help="The asethetic score threshold.")
|
||||
parser.add_argument(
|
||||
"--asethetic_score_siglip_metadata_path", type=str, default=None, help="The path to the video quality metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_asethetic_score_siglip", type=float, default=4.0, help="The asethetic score (SigLIP) threshold.")
|
||||
parser.add_argument(
|
||||
"--text_score_metadata_path", type=str, default=None, help="The path to the video text score metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_text_score", type=float, default=0.02, help="The text threshold.")
|
||||
parser.add_argument(
|
||||
"--motion_score_metadata_path", type=str, default=None, help="The path to the video motion score metadata (csv/jsonl)."
|
||||
)
|
||||
parser.add_argument("--min_motion_score", type=float, default=2, help="The motion threshold.")
|
||||
|
||||
args = parser.parse_args()
|
||||
return args
|
||||
|
||||
|
||||
def main(args):
|
||||
if args.video_metadata_path.endswith(".csv"):
|
||||
video_metadata_df = pd.read_csv(args.video_metadata_path)
|
||||
elif args.video_metadata_path.endswith(".jsonl"):
|
||||
video_metadata_df = pd.read_json(args.video_metadata_path, lines=True)
|
||||
else:
|
||||
raise ValueError("The video_metadata_path must end with .csv or .jsonl.")
|
||||
video_path_list = video_metadata_df[args.video_path_column].tolist()
|
||||
video_path_list = [os.path.basename(video_path) for video_path in video_path_list]
|
||||
|
||||
if not (args.saved_path.endswith(".csv") or args.saved_path.endswith(".jsonl")):
|
||||
raise ValueError("The saved_path must end with .csv or .jsonl.")
|
||||
|
||||
if os.path.exists(args.saved_path):
|
||||
if args.saved_path.endswith(".csv"):
|
||||
saved_metadata_df = pd.read_csv(args.saved_path)
|
||||
elif args.saved_path.endswith(".jsonl"):
|
||||
saved_metadata_df = pd.read_json(args.saved_path, lines=True)
|
||||
saved_video_path_list = saved_metadata_df[args.video_path_column].tolist()
|
||||
video_path_list = list(set(video_path_list).difference(set(saved_video_path_list)))
|
||||
logger.info(
|
||||
f"Resume from {args.saved_path}: {len(saved_video_path_list)} processed and {len(video_path_list)} to be processed."
|
||||
)
|
||||
|
||||
video_path_list = filter(
|
||||
video_path_list,
|
||||
basic_metadata_path=args.basic_metadata_path,
|
||||
min_resolution=args.min_resolution,
|
||||
min_duration=args.min_duration,
|
||||
max_duration=args.max_duration,
|
||||
asethetic_score_metadata_path=args.asethetic_score_metadata_path,
|
||||
min_asethetic_score=args.min_asethetic_score,
|
||||
asethetic_score_siglip_metadata_path=args.asethetic_score_siglip_metadata_path,
|
||||
min_asethetic_score_siglip=args.min_asethetic_score_siglip,
|
||||
text_score_metadata_path=args.text_score_metadata_path,
|
||||
min_text_score=args.min_text_score,
|
||||
motion_score_metadata_path=args.motion_score_metadata_path,
|
||||
min_motion_score=args.min_motion_score,
|
||||
)
|
||||
video_path_list = [os.path.join(args.video_folder, video_path) for video_path in video_path_list]
|
||||
# Sorting to guarantee the same result for each process.
|
||||
video_path_list = natsorted(video_path_list)
|
||||
|
||||
state = PartialState()
|
||||
|
||||
# Accelerate model initialization
|
||||
setattr(torch.nn.Linear, "reset_parameters", lambda self: None)
|
||||
setattr(torch.nn.LayerNorm, "reset_parameters", lambda self: None)
|
||||
torch.nn.init.kaiming_uniform_ = skip
|
||||
torch.nn.init.kaiming_normal_ = skip
|
||||
torch.nn.init.uniform_ = skip
|
||||
torch.nn.init.normal_ = skip
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(os.path.join(args.model_path, "llm"), use_fast=False)
|
||||
tinychat.utils.constants.LLAVA_DEFAULT_IMAGE_PATCH_TOKEN_IDX = (
|
||||
tokenizer.convert_tokens_to_ids(
|
||||
[tinychat.utils.constants.LLAVA_DEFAULT_IMAGE_PATCH_TOKEN]
|
||||
)[0]
|
||||
)
|
||||
config = AutoConfig.from_pretrained(args.model_path, trust_remote_code=True)
|
||||
model = VilaLlamaForCausalLM(config).half()
|
||||
tinychat.utils.constants.LLAVA_DEFAULT_IMAGE_PATCH_TOKEN_IDX = (
|
||||
tokenizer.convert_tokens_to_ids(
|
||||
[tinychat.utils.constants.LLAVA_DEFAULT_IMAGE_PATCH_TOKEN]
|
||||
)[0]
|
||||
)
|
||||
vision_tower = model.get_vision_tower()
|
||||
# if not vision_tower.is_loaded:
|
||||
# vision_tower.load_model()
|
||||
image_processor = vision_tower.image_processor
|
||||
# vision_tower = vision_tower.half()
|
||||
|
||||
if args.precision == "W16A16":
|
||||
pbar = tqdm(range(1))
|
||||
pbar.set_description("Loading checkpoint shards")
|
||||
for i in pbar:
|
||||
model.llm = load_checkpoint_and_dispatch(
|
||||
model.llm,
|
||||
os.path.join(args.model_path, "llm"),
|
||||
no_split_module_classes=[
|
||||
"OPTDecoderLayer",
|
||||
"LlamaDecoderLayer",
|
||||
"BloomBlock",
|
||||
"MPTBlock",
|
||||
"DecoderLayer",
|
||||
"CLIPEncoderLayer",
|
||||
],
|
||||
).to(state.device)
|
||||
model = model.to(state.device)
|
||||
|
||||
elif args.precision == "W4A16":
|
||||
from tinychat.utils.load_quant import load_awq_model
|
||||
# Auto load quant_path from the 3b/8b/13b/40b model.
|
||||
if args.quant_path is None:
|
||||
if "VILA1.5-3b-s2-AWQ" in args.model_path:
|
||||
args.quant_path = os.path.join(args.model_path, "llm/vila-1.5-3b-s2-w4-g128-awq-v2.pt")
|
||||
elif "VILA1.5-3b-AWQ" in args.model_path:
|
||||
args.quant_path = os.path.join(args.model_path, "llm/vila-1.5-3b-w4-g128-awq-v2.pt")
|
||||
elif "Llama-3-VILA1.5-8b-AWQ" in args.model_path:
|
||||
args.quant_path = os.path.join(args.model_path, "llm/llama-3-vila1.5-8b-w4-g128-awq-v2.pt")
|
||||
elif "VILA1.5-13b-AWQ" in args.model_path:
|
||||
args.quant_path = os.path.join(args.model_path, "llm/vila-1.5-13b-w4-g128-awq-v2.pt")
|
||||
elif "VILA1.5-40b-AWQ" in args.model_path:
|
||||
args.quant_path = os.path.join(args.model_path, "llm/vila-1.5-40b-w4-g128-awq-v2.pt")
|
||||
model.llm = load_awq_model(model.llm, args.quant_path, 4, 128, state.device)
|
||||
from tinychat.modules import (
|
||||
make_fused_mlp,
|
||||
make_fused_vision_attn,
|
||||
make_quant_attn,
|
||||
make_quant_norm,
|
||||
)
|
||||
|
||||
make_quant_attn(model.llm, state.device)
|
||||
make_quant_norm(model.llm)
|
||||
# make_fused_mlp(model)
|
||||
# make_fused_vision_attn(model,state.device)
|
||||
model = model.to(state.device)
|
||||
|
||||
else:
|
||||
raise NotImplementedError(f"Precision {args.precision} is not supported.")
|
||||
|
||||
device_warmup(state.device)
|
||||
tune_llava_patch_embedding(vision_tower, device=state.device)
|
||||
|
||||
stream_generator = LlavaStreamGenerator
|
||||
|
||||
model_prompter = get_prompter(
|
||||
args.model_type, args.model_path, False, False
|
||||
)
|
||||
stop_token_ids = get_stop_token_ids(args.model_type, args.model_path)
|
||||
|
||||
model.eval()
|
||||
|
||||
index = len(video_path_list) - len(video_path_list) % state.num_processes
|
||||
# Avoid the NCCL timeout in the final gather operation.
|
||||
logger.info(f"Drop {len(video_path_list) % state.num_processes} videos to ensure each process handles the same number of videos.")
|
||||
video_path_list = video_path_list[:index]
|
||||
logger.info(f"{len(video_path_list)} videos are to be processed.")
|
||||
|
||||
result_dict = {args.video_path_column: [], args.caption_column: []}
|
||||
with state.split_between_processes(video_path_list) as splitted_video_path_list:
|
||||
# TODO: Use VideoDataset.
|
||||
for i, video_path in enumerate(tqdm(splitted_video_path_list)):
|
||||
try:
|
||||
image_list = extract_uniform_frames(video_path, args.num_sampled_frames)
|
||||
image_num = len(image_list)
|
||||
# Similar operation in model_worker.py
|
||||
image_tensor = process_images(image_list, image_processor, model.config)
|
||||
if type(image_tensor) is list:
|
||||
image_tensor = [
|
||||
image.to(state.device, dtype=torch.float16) for image in image_tensor
|
||||
]
|
||||
else:
|
||||
image_tensor = image_tensor.to(state.device, dtype=torch.float16)
|
||||
|
||||
input_prompt = args.input_prompt
|
||||
# Insert image here
|
||||
image_token = get_image_token(model, args.model_path)
|
||||
image_token_holder = tinychat.utils.constants.LLAVA_DEFAULT_IM_TOKEN_PLACE_HOLDER
|
||||
im_token_count = input_prompt.count(image_token_holder)
|
||||
if im_token_count == 0:
|
||||
model_prompter.insert_prompt(image_token * image_num + input_prompt)
|
||||
else:
|
||||
assert im_token_count == image_num
|
||||
input_prompt = input_prompt.replace(image_token_holder, image_token)
|
||||
model_prompter.insert_prompt(input_prompt)
|
||||
output_stream = stream_generator(
|
||||
model,
|
||||
tokenizer,
|
||||
model_prompter.model_input,
|
||||
gen_params,
|
||||
device=state.device,
|
||||
stop_token_ids=stop_token_ids,
|
||||
image_tensor=image_tensor,
|
||||
)
|
||||
outputs = stream_output(output_stream)
|
||||
if len(outputs) != 0:
|
||||
result_dict[args.video_path_column].append(Path(video_path).name)
|
||||
result_dict[args.caption_column].append(outputs)
|
||||
|
||||
except Exception as e:
|
||||
logger.warning(f"VILA with {video_path} failed. Error is {e}.")
|
||||
|
||||
if i != 0 and i % args.saved_freq == 0:
|
||||
state.wait_for_everyone()
|
||||
gathered_result_dict = {k: gather_object(v) for k, v in result_dict.items()}
|
||||
if state.is_main_process and len(gathered_result_dict[args.video_path_column]) != 0:
|
||||
result_df = pd.DataFrame(gathered_result_dict)
|
||||
if args.saved_path.endswith(".csv"):
|
||||
header = False if os.path.exists(args.saved_path) else True
|
||||
result_df.to_csv(args.saved_path, header=header, index=False, mode="a")
|
||||
elif args.saved_path.endswith(".jsonl"):
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, mode="a", force_ascii=False)
|
||||
logger.info(f"Save result to {args.saved_path}.")
|
||||
for k in result_dict.keys():
|
||||
result_dict[k] = []
|
||||
|
||||
state.wait_for_everyone()
|
||||
gathered_result_dict = {k: gather_object(v) for k, v in result_dict.items()}
|
||||
if state.is_main_process and len(gathered_result_dict[args.video_path_column]) != 0:
|
||||
result_df = pd.DataFrame(gathered_result_dict)
|
||||
if args.saved_path.endswith(".csv"):
|
||||
header = False if os.path.exists(args.saved_path) else True
|
||||
result_df.to_csv(args.saved_path, header=header, index=False, mode="a")
|
||||
elif args.saved_path.endswith(".jsonl"):
|
||||
result_df.to_json(args.saved_path, orient="records", lines=True, mode="a", force_ascii=False)
|
||||
logger.info(f"Save result to {args.saved_path}.")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
args = parse_args()
|
||||
main(args)
|
||||
@@ -1,65 +1,62 @@
|
||||
# ComfyUI CogVideoX-Fun
|
||||
Easily use CogVideoX-Fun inside ComfyUI!
|
||||
# ComfyUI VideoX-Fun
|
||||
Easily use VideoX-Fun inside ComfyUI!
|
||||
|
||||
- [Installation](#1-installation)
|
||||
- [Node types](#node-types)
|
||||
- [Example workflows](#example-workflows)
|
||||
|
||||
## 1. Installation
|
||||
## Installation
|
||||
### 1. ComfyUI Installation
|
||||
|
||||
### Option 1: Install via ComfyUI Manager
|
||||
TBD
|
||||
#### Option 1: Install via ComfyUI Manager
|
||||
|
||||
|
||||
### Option 2: Install manually
|
||||
The CogVideoX-Fun repository needs to be placed at `ComfyUI/custom_nodes/CogVideoX-Fun/`.
|
||||
#### Option 2: Install manually
|
||||
The VideoX-Fun repository needs to be placed at `ComfyUI/custom_nodes/VideoX-Fun/`.
|
||||
|
||||
```
|
||||
cd ComfyUI/custom_nodes/
|
||||
|
||||
# Git clone the cogvideox_fun itself
|
||||
git clone https://github.com/aigc-apps/CogVideoX-Fun.git
|
||||
git clone https://github.com/aigc-apps/VideoX-Fun.git
|
||||
|
||||
# Git clone the video outout node
|
||||
git clone https://github.com/Kosinkadink/ComfyUI-VideoHelperSuite.git
|
||||
|
||||
cd CogVideoX-Fun/
|
||||
# Git clone the KJ Nodes
|
||||
git clone https://github.com/kijai/ComfyUI-KJNodes.git
|
||||
|
||||
cd VideoX-Fun/
|
||||
python install.py
|
||||
```
|
||||
|
||||
### 2. Download models into `ComfyUI/models/CogVideoX-Fun/`
|
||||
### 2. Download models
|
||||
#### i、Full loading
|
||||
Download full model into `ComfyUI/models/Fun_Models/`.
|
||||
|
||||
| Name | Storage Space | Url | Hugging Face | Description |
|
||||
|--|--|--|--|--|
|
||||
| CogVideoX-Fun-2b-InP.tar.gz | Before extraction:9.69 GB \/ After extraction: 13.0 GB | [Download](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/Diffusion_Transformer/CogVideoX-Fun-2b-InP.tar.gz) | [🤗Link](https://huggingface.co/alibaba-pai/CogVideoX-Fun-2b-InP)| Our official graph-generated video model is capable of predicting videos at multiple resolutions (512, 768, 1024, 1280) and has been trained on 144 frames at a rate of 24 frames per second. |
|
||||
#### ii、Chunked loading
|
||||
Put the transformer model weights to the `ComfyUI/models/diffusion_models/`.
|
||||
Put the text encoer model weights to the `ComfyUI/models/text_encoders/`.
|
||||
Put the clip vision model weights to the `ComfyUI/models/clip_vision/`.
|
||||
Put the vae model weights to the `ComfyUI/models/vae/`.
|
||||
Put the tokenizer files to the `ComfyUI/models/Fun_Models/` (For example: `ComfyUI/models/Fun_Models/umt5-xxl`).
|
||||
|
||||
## Node types
|
||||
- **LoadCogVideoX_Fun_Model**
|
||||
- Loads the CogVideoX-Fun model
|
||||
- **TextBox**
|
||||
- Write the prompt for CogVideoX-Fun model
|
||||
- **CogVideoX_Fun_I2VSampler**
|
||||
- CogVideoX-Fun Sampler for Image to Video
|
||||
- **CogVideoX_Fun_T2VSampler**
|
||||
- CogVideoX-Fun Sampler for Text to Video
|
||||
- **CogVideoX_Fun_V2VSampler**
|
||||
- CogVideoX-Fun Sampler for Video to Video
|
||||
### 3. (Optional) Download preprocess weights into `ComfyUI/custom_nodes/Fun_Models/Third_Party/`.
|
||||
Except for the fun models' weights, if you want to use the control preprocess nodes, you can download the preprocess weights to `ComfyUI/custom_nodes/Fun_Models/Third_Party/`.
|
||||
|
||||
## Example workflows
|
||||
```
|
||||
remote_onnx_det = "https://huggingface.co/yzd-v/DWPose/resolve/main/yolox_l.onnx"
|
||||
remote_onnx_pose = "https://huggingface.co/yzd-v/DWPose/resolve/main/dw-ll_ucoco_384.onnx"
|
||||
remote_zoe= "https://huggingface.co/lllyasviel/Annotators/resolve/main/ZoeD_M12_N.pt"
|
||||
```
|
||||
|
||||
### Video to video generation
|
||||
Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/cogvideoxfunv1_workflow_v2v.json) of the json:
|
||||

|
||||
## Support models
|
||||
|
||||
You can run the demo using following video:
|
||||
[demo video](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/play_guitar.mp4)
|
||||
|
||||
### Image to video generation
|
||||
Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/cogvideoxfunv1_workflow_i2v.json) of the json:
|
||||

|
||||
|
||||
You can run the demo using following photo:
|
||||

|
||||
|
||||
### Text to video generation
|
||||
Our ui is shown as follow, this is the [download link](https://pai-aigc-photog.oss-cn-hangzhou.aliyuncs.com/cogvideox_fun/asset/v1/cogvideoxfunv1_workflow_t2v.json) of the json:
|
||||

|
||||
- [CogVideox-Fun](cogvideox_fun/README.md)
|
||||
- [Qwen-Image](qwenimage/README.md)
|
||||
- [Wan2.1](wan2_1/README.md)
|
||||
- [Wan2.2](wan2_2/README.md)
|
||||
- [Wan2.1-Fun](wan2_1_fun/README.md)
|
||||
- [Wan2.2-Fun](wan2_2_fun/README.md)
|
||||
- [Wan2.2-VACE-Fun](wan2_2_fun/README.md)
|
||||
- [Z-Image](z_image/README.md)
|
||||
@@ -0,0 +1,46 @@
|
||||
# This folder is modified from the https://github.com/Mikubill/sd-webui-controlnet
|
||||
# Openpose
|
||||
# Original from CMU https://github.com/CMU-Perceptual-Computing-Lab/openpose
|
||||
# 2nd Edited by https://github.com/Hzzone/pytorch-openpose
|
||||
# 3rd Edited by ControlNet
|
||||
# 4th Edited by ControlNet (added face and correct hands)
|
||||
|
||||
import os
|
||||
|
||||
os.environ["KMP_DUPLICATE_LIB_OK"]="TRUE"
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
from . import util
|
||||
from .wholebody import Wholebody
|
||||
|
||||
|
||||
def draw_pose(poses, H, W):
|
||||
canvas = np.zeros(shape=(H, W, 3), dtype=np.uint8)
|
||||
|
||||
for pose in poses:
|
||||
canvas = util.draw_bodypose(canvas, pose.body.keypoints)
|
||||
|
||||
canvas = util.draw_handpose(canvas, pose.left_hand)
|
||||
canvas = util.draw_handpose(canvas, pose.right_hand)
|
||||
|
||||
canvas = util.draw_facepose(canvas, pose.face)
|
||||
return canvas
|
||||
|
||||
|
||||
class DWposeDetector:
|
||||
def __init__(self, onnx_det, onnx_pose):
|
||||
self.pose_estimation = Wholebody(onnx_det, onnx_pose)
|
||||
|
||||
def __call__(self, oriImg):
|
||||
oriImg = oriImg.copy()
|
||||
H, W, C = oriImg.shape
|
||||
with torch.no_grad():
|
||||
keypoints_info = self.pose_estimation(oriImg)
|
||||
return draw_pose(
|
||||
Wholebody.format_result(keypoints_info),
|
||||
H,
|
||||
W,
|
||||
)
|
||||
|
||||
@@ -0,0 +1,129 @@
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
|
||||
def nms(boxes, scores, nms_thr):
|
||||
"""Single class NMS implemented in Numpy."""
|
||||
x1 = boxes[:, 0]
|
||||
y1 = boxes[:, 1]
|
||||
x2 = boxes[:, 2]
|
||||
y2 = boxes[:, 3]
|
||||
|
||||
areas = (x2 - x1 + 1) * (y2 - y1 + 1)
|
||||
order = scores.argsort()[::-1]
|
||||
|
||||
keep = []
|
||||
while order.size > 0:
|
||||
i = order[0]
|
||||
keep.append(i)
|
||||
xx1 = np.maximum(x1[i], x1[order[1:]])
|
||||
yy1 = np.maximum(y1[i], y1[order[1:]])
|
||||
xx2 = np.minimum(x2[i], x2[order[1:]])
|
||||
yy2 = np.minimum(y2[i], y2[order[1:]])
|
||||
|
||||
w = np.maximum(0.0, xx2 - xx1 + 1)
|
||||
h = np.maximum(0.0, yy2 - yy1 + 1)
|
||||
inter = w * h
|
||||
ovr = inter / (areas[i] + areas[order[1:]] - inter)
|
||||
|
||||
inds = np.where(ovr <= nms_thr)[0]
|
||||
order = order[inds + 1]
|
||||
|
||||
return keep
|
||||
|
||||
def multiclass_nms(boxes, scores, nms_thr, score_thr):
|
||||
"""Multiclass NMS implemented in Numpy. Class-aware version."""
|
||||
final_dets = []
|
||||
num_classes = scores.shape[1]
|
||||
for cls_ind in range(num_classes):
|
||||
cls_scores = scores[:, cls_ind]
|
||||
valid_score_mask = cls_scores > score_thr
|
||||
if valid_score_mask.sum() == 0:
|
||||
continue
|
||||
else:
|
||||
valid_scores = cls_scores[valid_score_mask]
|
||||
valid_boxes = boxes[valid_score_mask]
|
||||
keep = nms(valid_boxes, valid_scores, nms_thr)
|
||||
if len(keep) > 0:
|
||||
cls_inds = np.ones((len(keep), 1)) * cls_ind
|
||||
dets = np.concatenate(
|
||||
[valid_boxes[keep], valid_scores[keep, None], cls_inds], 1
|
||||
)
|
||||
final_dets.append(dets)
|
||||
if len(final_dets) == 0:
|
||||
return None
|
||||
return np.concatenate(final_dets, 0)
|
||||
|
||||
def demo_postprocess(outputs, img_size, p6=False):
|
||||
grids = []
|
||||
expanded_strides = []
|
||||
strides = [8, 16, 32] if not p6 else [8, 16, 32, 64]
|
||||
|
||||
hsizes = [img_size[0] // stride for stride in strides]
|
||||
wsizes = [img_size[1] // stride for stride in strides]
|
||||
|
||||
for hsize, wsize, stride in zip(hsizes, wsizes, strides):
|
||||
xv, yv = np.meshgrid(np.arange(wsize), np.arange(hsize))
|
||||
grid = np.stack((xv, yv), 2).reshape(1, -1, 2)
|
||||
grids.append(grid)
|
||||
shape = grid.shape[:2]
|
||||
expanded_strides.append(np.full((*shape, 1), stride))
|
||||
|
||||
grids = np.concatenate(grids, 1)
|
||||
expanded_strides = np.concatenate(expanded_strides, 1)
|
||||
outputs[..., :2] = (outputs[..., :2] + grids) * expanded_strides
|
||||
outputs[..., 2:4] = np.exp(outputs[..., 2:4]) * expanded_strides
|
||||
|
||||
return outputs
|
||||
|
||||
def preprocess(img, input_size, swap=(2, 0, 1)):
|
||||
if len(img.shape) == 3:
|
||||
padded_img = np.ones((input_size[0], input_size[1], 3), dtype=np.uint8) * 114
|
||||
else:
|
||||
padded_img = np.ones(input_size, dtype=np.uint8) * 114
|
||||
|
||||
r = min(input_size[0] / img.shape[0], input_size[1] / img.shape[1])
|
||||
resized_img = cv2.resize(
|
||||
img,
|
||||
(int(img.shape[1] * r), int(img.shape[0] * r)),
|
||||
interpolation=cv2.INTER_LINEAR,
|
||||
).astype(np.uint8)
|
||||
padded_img[: int(img.shape[0] * r), : int(img.shape[1] * r)] = resized_img
|
||||
|
||||
padded_img = padded_img.transpose(swap)
|
||||
padded_img = np.ascontiguousarray(padded_img, dtype=np.float32)
|
||||
return padded_img, r
|
||||
|
||||
def inference_detector(session, oriImg, detect_classes=[0]):
|
||||
input_shape = (640,640)
|
||||
img, ratio = preprocess(oriImg, input_shape)
|
||||
|
||||
input = img[None, :, :, :]
|
||||
if "InferenceSession" in type(session).__name__:
|
||||
input_name = session.get_inputs()[0].name
|
||||
output = session.run(None, {input_name: input})
|
||||
else:
|
||||
outNames = session.getUnconnectedOutLayersNames()
|
||||
session.setInput(input)
|
||||
output = session.forward(outNames)
|
||||
|
||||
predictions = demo_postprocess(output[0], input_shape)[0]
|
||||
|
||||
boxes = predictions[:, :4]
|
||||
scores = predictions[:, 4:5] * predictions[:, 5:]
|
||||
|
||||
boxes_xyxy = np.ones_like(boxes)
|
||||
boxes_xyxy[:, 0] = boxes[:, 0] - boxes[:, 2]/2.
|
||||
boxes_xyxy[:, 1] = boxes[:, 1] - boxes[:, 3]/2.
|
||||
boxes_xyxy[:, 2] = boxes[:, 0] + boxes[:, 2]/2.
|
||||
boxes_xyxy[:, 3] = boxes[:, 1] + boxes[:, 3]/2.
|
||||
boxes_xyxy /= ratio
|
||||
dets = multiclass_nms(boxes_xyxy, scores, nms_thr=0.45, score_thr=0.1)
|
||||
if dets is None:
|
||||
return None
|
||||
final_boxes, final_scores, final_cls_inds = dets[:, :4], dets[:, 4], dets[:, 5]
|
||||
isscore = final_scores>0.3
|
||||
iscat = np.isin(final_cls_inds, detect_classes)
|
||||
isbbox = [ i and j for (i, j) in zip(isscore, iscat)]
|
||||
final_boxes = final_boxes[isbbox]
|
||||
return final_boxes
|
||||
@@ -0,0 +1,365 @@
|
||||
from typing import List, Tuple
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
|
||||
def preprocess(
|
||||
img: np.ndarray, out_bbox, input_size: Tuple[int, int] = (192, 256)
|
||||
) -> Tuple[np.ndarray, np.ndarray, np.ndarray]:
|
||||
"""Do preprocessing for DWPose model inference.
|
||||
|
||||
Args:
|
||||
img (np.ndarray): Input image in shape.
|
||||
input_size (tuple): Input image size in shape (w, h).
|
||||
|
||||
Returns:
|
||||
tuple:
|
||||
- resized_img (np.ndarray): Preprocessed image.
|
||||
- center (np.ndarray): Center of image.
|
||||
- scale (np.ndarray): Scale of image.
|
||||
"""
|
||||
# get shape of image
|
||||
img_shape = img.shape[:2]
|
||||
out_img, out_center, out_scale = [], [], []
|
||||
if len(out_bbox) == 0:
|
||||
out_bbox = [[0, 0, img_shape[1], img_shape[0]]]
|
||||
for i in range(len(out_bbox)):
|
||||
x0 = out_bbox[i][0]
|
||||
y0 = out_bbox[i][1]
|
||||
x1 = out_bbox[i][2]
|
||||
y1 = out_bbox[i][3]
|
||||
bbox = np.array([x0, y0, x1, y1])
|
||||
|
||||
# get center and scale
|
||||
center, scale = bbox_xyxy2cs(bbox, padding=1.25)
|
||||
|
||||
# do affine transformation
|
||||
resized_img, scale = top_down_affine(input_size, scale, center, img)
|
||||
|
||||
# normalize image
|
||||
mean = np.array([123.675, 116.28, 103.53])
|
||||
std = np.array([58.395, 57.12, 57.375])
|
||||
resized_img = (resized_img - mean) / std
|
||||
|
||||
out_img.append(resized_img)
|
||||
out_center.append(center)
|
||||
out_scale.append(scale)
|
||||
|
||||
return out_img, out_center, out_scale
|
||||
|
||||
|
||||
def inference(sess, img):
|
||||
"""Inference DWPose model.
|
||||
|
||||
Args:
|
||||
sess : ONNXRuntime session.
|
||||
img : Input image in shape.
|
||||
|
||||
Returns:
|
||||
outputs : Output of DWPose model.
|
||||
"""
|
||||
all_out = []
|
||||
# build input
|
||||
input = np.stack(img, axis=0).transpose(0, 3, 1, 2)
|
||||
input = input.astype(np.float32)
|
||||
if "InferenceSession" in type(sess).__name__:
|
||||
input_name = sess.get_inputs()[0].name
|
||||
all_outputs = sess.run(None, {input_name: input})
|
||||
for batch_idx in range(len(all_outputs[0])):
|
||||
outputs = [all_outputs[i][batch_idx:batch_idx+1,...] for i in range(len(all_outputs))]
|
||||
all_out.append(outputs)
|
||||
return all_out
|
||||
|
||||
for i in range(len(img)):
|
||||
|
||||
input = img[i].transpose(2, 0, 1)
|
||||
input = input[None, :, :, :]
|
||||
|
||||
outNames = sess.getUnconnectedOutLayersNames()
|
||||
sess.setInput(input)
|
||||
outputs = sess.forward(outNames)
|
||||
all_out.append(outputs)
|
||||
|
||||
return all_out
|
||||
|
||||
|
||||
def postprocess(outputs: List[np.ndarray],
|
||||
model_input_size: Tuple[int, int],
|
||||
center: Tuple[int, int],
|
||||
scale: Tuple[int, int],
|
||||
simcc_split_ratio: float = 2.0
|
||||
) -> Tuple[np.ndarray, np.ndarray]:
|
||||
"""Postprocess for DWPose model output.
|
||||
|
||||
Args:
|
||||
outputs (np.ndarray): Output of RTMPose model.
|
||||
model_input_size (tuple): RTMPose model Input image size.
|
||||
center (tuple): Center of bbox in shape (x, y).
|
||||
scale (tuple): Scale of bbox in shape (w, h).
|
||||
simcc_split_ratio (float): Split ratio of simcc.
|
||||
|
||||
Returns:
|
||||
tuple:
|
||||
- keypoints (np.ndarray): Rescaled keypoints.
|
||||
- scores (np.ndarray): Model predict scores.
|
||||
"""
|
||||
all_key = []
|
||||
all_score = []
|
||||
for i in range(len(outputs)):
|
||||
# use simcc to decode
|
||||
simcc_x, simcc_y = outputs[i]
|
||||
keypoints, scores = decode(simcc_x, simcc_y, simcc_split_ratio)
|
||||
|
||||
# rescale keypoints
|
||||
keypoints = keypoints / model_input_size * scale[i] + center[i] - scale[i] / 2
|
||||
all_key.append(keypoints[0])
|
||||
all_score.append(scores[0])
|
||||
|
||||
return np.array(all_key), np.array(all_score)
|
||||
|
||||
|
||||
def bbox_xyxy2cs(bbox: np.ndarray,
|
||||
padding: float = 1.) -> Tuple[np.ndarray, np.ndarray]:
|
||||
"""Transform the bbox format from (x,y,w,h) into (center, scale)
|
||||
|
||||
Args:
|
||||
bbox (ndarray): Bounding box(es) in shape (4,) or (n, 4), formatted
|
||||
as (left, top, right, bottom)
|
||||
padding (float): BBox padding factor that will be multilied to scale.
|
||||
Default: 1.0
|
||||
|
||||
Returns:
|
||||
tuple: A tuple containing center and scale.
|
||||
- np.ndarray[float32]: Center (x, y) of the bbox in shape (2,) or
|
||||
(n, 2)
|
||||
- np.ndarray[float32]: Scale (w, h) of the bbox in shape (2,) or
|
||||
(n, 2)
|
||||
"""
|
||||
# convert single bbox from (4, ) to (1, 4)
|
||||
dim = bbox.ndim
|
||||
if dim == 1:
|
||||
bbox = bbox[None, :]
|
||||
|
||||
# get bbox center and scale
|
||||
x1, y1, x2, y2 = np.hsplit(bbox, [1, 2, 3])
|
||||
center = np.hstack([x1 + x2, y1 + y2]) * 0.5
|
||||
scale = np.hstack([x2 - x1, y2 - y1]) * padding
|
||||
|
||||
if dim == 1:
|
||||
center = center[0]
|
||||
scale = scale[0]
|
||||
|
||||
return center, scale
|
||||
|
||||
|
||||
def _fix_aspect_ratio(bbox_scale: np.ndarray,
|
||||
aspect_ratio: float) -> np.ndarray:
|
||||
"""Extend the scale to match the given aspect ratio.
|
||||
|
||||
Args:
|
||||
scale (np.ndarray): The image scale (w, h) in shape (2, )
|
||||
aspect_ratio (float): The ratio of ``w/h``
|
||||
|
||||
Returns:
|
||||
np.ndarray: The reshaped image scale in (2, )
|
||||
"""
|
||||
w, h = np.hsplit(bbox_scale, [1])
|
||||
bbox_scale = np.where(w > h * aspect_ratio,
|
||||
np.hstack([w, w / aspect_ratio]),
|
||||
np.hstack([h * aspect_ratio, h]))
|
||||
return bbox_scale
|
||||
|
||||
|
||||
def _rotate_point(pt: np.ndarray, angle_rad: float) -> np.ndarray:
|
||||
"""Rotate a point by an angle.
|
||||
|
||||
Args:
|
||||
pt (np.ndarray): 2D point coordinates (x, y) in shape (2, )
|
||||
angle_rad (float): rotation angle in radian
|
||||
|
||||
Returns:
|
||||
np.ndarray: Rotated point in shape (2, )
|
||||
"""
|
||||
sn, cs = np.sin(angle_rad), np.cos(angle_rad)
|
||||
rot_mat = np.array([[cs, -sn], [sn, cs]])
|
||||
return rot_mat @ pt
|
||||
|
||||
|
||||
def _get_3rd_point(a: np.ndarray, b: np.ndarray) -> np.ndarray:
|
||||
"""To calculate the affine matrix, three pairs of points are required. This
|
||||
function is used to get the 3rd point, given 2D points a & b.
|
||||
|
||||
The 3rd point is defined by rotating vector `a - b` by 90 degrees
|
||||
anticlockwise, using b as the rotation center.
|
||||
|
||||
Args:
|
||||
a (np.ndarray): The 1st point (x,y) in shape (2, )
|
||||
b (np.ndarray): The 2nd point (x,y) in shape (2, )
|
||||
|
||||
Returns:
|
||||
np.ndarray: The 3rd point.
|
||||
"""
|
||||
direction = a - b
|
||||
c = b + np.r_[-direction[1], direction[0]]
|
||||
return c
|
||||
|
||||
|
||||
def get_warp_matrix(center: np.ndarray,
|
||||
scale: np.ndarray,
|
||||
rot: float,
|
||||
output_size: Tuple[int, int],
|
||||
shift: Tuple[float, float] = (0., 0.),
|
||||
inv: bool = False) -> np.ndarray:
|
||||
"""Calculate the affine transformation matrix that can warp the bbox area
|
||||
in the input image to the output size.
|
||||
|
||||
Args:
|
||||
center (np.ndarray[2, ]): Center of the bounding box (x, y).
|
||||
scale (np.ndarray[2, ]): Scale of the bounding box
|
||||
wrt [width, height].
|
||||
rot (float): Rotation angle (degree).
|
||||
output_size (np.ndarray[2, ] | list(2,)): Size of the
|
||||
destination heatmaps.
|
||||
shift (0-100%): Shift translation ratio wrt the width/height.
|
||||
Default (0., 0.).
|
||||
inv (bool): Option to inverse the affine transform direction.
|
||||
(inv=False: src->dst or inv=True: dst->src)
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 2x3 transformation matrix
|
||||
"""
|
||||
shift = np.array(shift)
|
||||
src_w = scale[0]
|
||||
dst_w = output_size[0]
|
||||
dst_h = output_size[1]
|
||||
|
||||
# compute transformation matrix
|
||||
rot_rad = np.deg2rad(rot)
|
||||
src_dir = _rotate_point(np.array([0., src_w * -0.5]), rot_rad)
|
||||
dst_dir = np.array([0., dst_w * -0.5])
|
||||
|
||||
# get four corners of the src rectangle in the original image
|
||||
src = np.zeros((3, 2), dtype=np.float32)
|
||||
src[0, :] = center + scale * shift
|
||||
src[1, :] = center + src_dir + scale * shift
|
||||
src[2, :] = _get_3rd_point(src[0, :], src[1, :])
|
||||
|
||||
# get four corners of the dst rectangle in the input image
|
||||
dst = np.zeros((3, 2), dtype=np.float32)
|
||||
dst[0, :] = [dst_w * 0.5, dst_h * 0.5]
|
||||
dst[1, :] = np.array([dst_w * 0.5, dst_h * 0.5]) + dst_dir
|
||||
dst[2, :] = _get_3rd_point(dst[0, :], dst[1, :])
|
||||
|
||||
if inv:
|
||||
warp_mat = cv2.getAffineTransform(np.float32(dst), np.float32(src))
|
||||
else:
|
||||
warp_mat = cv2.getAffineTransform(np.float32(src), np.float32(dst))
|
||||
|
||||
return warp_mat
|
||||
|
||||
|
||||
def top_down_affine(input_size: dict, bbox_scale: dict, bbox_center: dict,
|
||||
img: np.ndarray) -> Tuple[np.ndarray, np.ndarray]:
|
||||
"""Get the bbox image as the model input by affine transform.
|
||||
|
||||
Args:
|
||||
input_size (dict): The input size of the model.
|
||||
bbox_scale (dict): The bbox scale of the img.
|
||||
bbox_center (dict): The bbox center of the img.
|
||||
img (np.ndarray): The original image.
|
||||
|
||||
Returns:
|
||||
tuple: A tuple containing center and scale.
|
||||
- np.ndarray[float32]: img after affine transform.
|
||||
- np.ndarray[float32]: bbox scale after affine transform.
|
||||
"""
|
||||
w, h = input_size
|
||||
warp_size = (int(w), int(h))
|
||||
|
||||
# reshape bbox to fixed aspect ratio
|
||||
bbox_scale = _fix_aspect_ratio(bbox_scale, aspect_ratio=w / h)
|
||||
|
||||
# get the affine matrix
|
||||
center = bbox_center
|
||||
scale = bbox_scale
|
||||
rot = 0
|
||||
warp_mat = get_warp_matrix(center, scale, rot, output_size=(w, h))
|
||||
|
||||
# do affine transform
|
||||
img = cv2.warpAffine(img, warp_mat, warp_size, flags=cv2.INTER_LINEAR)
|
||||
|
||||
return img, bbox_scale
|
||||
|
||||
|
||||
def get_simcc_maximum(simcc_x: np.ndarray,
|
||||
simcc_y: np.ndarray) -> Tuple[np.ndarray, np.ndarray]:
|
||||
"""Get maximum response location and value from simcc representations.
|
||||
|
||||
Note:
|
||||
instance number: N
|
||||
num_keypoints: K
|
||||
heatmap height: H
|
||||
heatmap width: W
|
||||
|
||||
Args:
|
||||
simcc_x (np.ndarray): x-axis SimCC in shape (K, Wx) or (N, K, Wx)
|
||||
simcc_y (np.ndarray): y-axis SimCC in shape (K, Wy) or (N, K, Wy)
|
||||
|
||||
Returns:
|
||||
tuple:
|
||||
- locs (np.ndarray): locations of maximum heatmap responses in shape
|
||||
(K, 2) or (N, K, 2)
|
||||
- vals (np.ndarray): values of maximum heatmap responses in shape
|
||||
(K,) or (N, K)
|
||||
"""
|
||||
N, K, Wx = simcc_x.shape
|
||||
simcc_x = simcc_x.reshape(N * K, -1)
|
||||
simcc_y = simcc_y.reshape(N * K, -1)
|
||||
|
||||
# get maximum value locations
|
||||
x_locs = np.argmax(simcc_x, axis=1)
|
||||
y_locs = np.argmax(simcc_y, axis=1)
|
||||
locs = np.stack((x_locs, y_locs), axis=-1).astype(np.float32)
|
||||
max_val_x = np.amax(simcc_x, axis=1)
|
||||
max_val_y = np.amax(simcc_y, axis=1)
|
||||
|
||||
# get maximum value across x and y axis
|
||||
mask = max_val_x > max_val_y
|
||||
max_val_x[mask] = max_val_y[mask]
|
||||
vals = max_val_x
|
||||
locs[vals <= 0.] = -1
|
||||
|
||||
# reshape
|
||||
locs = locs.reshape(N, K, 2)
|
||||
vals = vals.reshape(N, K)
|
||||
|
||||
return locs, vals
|
||||
|
||||
|
||||
def decode(simcc_x: np.ndarray, simcc_y: np.ndarray,
|
||||
simcc_split_ratio) -> Tuple[np.ndarray, np.ndarray]:
|
||||
"""Modulate simcc distribution with Gaussian.
|
||||
|
||||
Args:
|
||||
simcc_x (np.ndarray[K, Wx]): model predicted simcc in x.
|
||||
simcc_y (np.ndarray[K, Wy]): model predicted simcc in y.
|
||||
simcc_split_ratio (int): The split ratio of simcc.
|
||||
|
||||
Returns:
|
||||
tuple: A tuple containing center and scale.
|
||||
- np.ndarray[float32]: keypoints in shape (K, 2) or (n, K, 2)
|
||||
- np.ndarray[float32]: scores in shape (K,) or (n, K)
|
||||
"""
|
||||
keypoints, scores = get_simcc_maximum(simcc_x, simcc_y)
|
||||
keypoints /= simcc_split_ratio
|
||||
|
||||
return keypoints, scores
|
||||
|
||||
|
||||
def inference_pose(session, out_bbox, oriImg, model_input_size: Tuple[int, int]= (288, 384) ):
|
||||
resized_img, center, scale = preprocess(oriImg, out_bbox, model_input_size)
|
||||
outputs = inference(session, resized_img)
|
||||
keypoints, scores = postprocess(outputs, model_input_size, center, scale)
|
||||
|
||||
return keypoints, scores
|
||||
@@ -0,0 +1,360 @@
|
||||
import math
|
||||
|
||||
import cv2
|
||||
import matplotlib
|
||||
import numpy as np
|
||||
|
||||
eps = 0.01
|
||||
|
||||
def smart_resize(x, s):
|
||||
Ht, Wt = s
|
||||
if x.ndim == 2:
|
||||
Ho, Wo = x.shape
|
||||
Co = 1
|
||||
else:
|
||||
Ho, Wo, Co = x.shape
|
||||
if Co == 3 or Co == 1:
|
||||
k = float(Ht + Wt) / float(Ho + Wo)
|
||||
return cv2.resize(x, (int(Wt), int(Ht)), interpolation=cv2.INTER_AREA if k < 1 else cv2.INTER_LANCZOS4)
|
||||
else:
|
||||
return np.stack([smart_resize(x[:, :, i], s) for i in range(Co)], axis=2)
|
||||
|
||||
def smart_resize_k(x, fx, fy):
|
||||
if x.ndim == 2:
|
||||
Ho, Wo = x.shape
|
||||
Co = 1
|
||||
else:
|
||||
Ho, Wo, Co = x.shape
|
||||
Ht, Wt = Ho * fy, Wo * fx
|
||||
if Co == 3 or Co == 1:
|
||||
k = float(Ht + Wt) / float(Ho + Wo)
|
||||
return cv2.resize(x, (int(Wt), int(Ht)), interpolation=cv2.INTER_AREA if k < 1 else cv2.INTER_LANCZOS4)
|
||||
else:
|
||||
return np.stack([smart_resize_k(x[:, :, i], fx, fy) for i in range(Co)], axis=2)
|
||||
|
||||
def padRightDownCorner(img, stride, padValue):
|
||||
h = img.shape[0]
|
||||
w = img.shape[1]
|
||||
|
||||
pad = 4 * [None]
|
||||
pad[0] = 0 # up
|
||||
pad[1] = 0 # left
|
||||
pad[2] = 0 if (h % stride == 0) else stride - (h % stride) # down
|
||||
pad[3] = 0 if (w % stride == 0) else stride - (w % stride) # right
|
||||
|
||||
img_padded = img
|
||||
pad_up = np.tile(img_padded[0:1, :, :]*0 + padValue, (pad[0], 1, 1))
|
||||
img_padded = np.concatenate((pad_up, img_padded), axis=0)
|
||||
pad_left = np.tile(img_padded[:, 0:1, :]*0 + padValue, (1, pad[1], 1))
|
||||
img_padded = np.concatenate((pad_left, img_padded), axis=1)
|
||||
pad_down = np.tile(img_padded[-2:-1, :, :]*0 + padValue, (pad[2], 1, 1))
|
||||
img_padded = np.concatenate((img_padded, pad_down), axis=0)
|
||||
pad_right = np.tile(img_padded[:, -2:-1, :]*0 + padValue, (1, pad[3], 1))
|
||||
img_padded = np.concatenate((img_padded, pad_right), axis=1)
|
||||
|
||||
return img_padded, pad
|
||||
|
||||
def transfer(model, model_weights):
|
||||
transfered_model_weights = {}
|
||||
for weights_name in model.state_dict().keys():
|
||||
transfered_model_weights[weights_name] = model_weights['.'.join(weights_name.split('.')[1:])]
|
||||
return transfered_model_weights
|
||||
|
||||
def is_normalized(keypoints) -> bool:
|
||||
point_normalized = [
|
||||
0 <= abs(k.x) <= 1 and 0 <= abs(k.y) <= 1
|
||||
for k in keypoints
|
||||
if k is not None
|
||||
]
|
||||
if not point_normalized:
|
||||
return False
|
||||
return all(point_normalized)
|
||||
|
||||
def draw_bodypose(canvas: np.ndarray, keypoints) -> np.ndarray:
|
||||
"""
|
||||
Draw keypoints and limbs representing body pose on a given canvas.
|
||||
|
||||
Args:
|
||||
canvas (np.ndarray): A 3D numpy array representing the canvas (image) on which to draw the body pose.
|
||||
keypoints (List[Keypoint]): A list of Keypoint objects representing the body keypoints to be drawn.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 3D numpy array representing the modified canvas with the drawn body pose.
|
||||
|
||||
Note:
|
||||
The function expects the x and y coordinates of the keypoints to be normalized between 0 and 1.
|
||||
"""
|
||||
if not is_normalized(keypoints):
|
||||
H, W = 1.0, 1.0
|
||||
else:
|
||||
H, W, _ = canvas.shape
|
||||
|
||||
stickwidth = 4
|
||||
|
||||
limbSeq = [
|
||||
[2, 3], [2, 6], [3, 4], [4, 5],
|
||||
[6, 7], [7, 8], [2, 9], [9, 10],
|
||||
[10, 11], [2, 12], [12, 13], [13, 14],
|
||||
[2, 1], [1, 15], [15, 17], [1, 16],
|
||||
[16, 18],
|
||||
]
|
||||
|
||||
colors = [[255, 0, 0], [255, 85, 0], [255, 170, 0], [255, 255, 0], [170, 255, 0], [85, 255, 0], [0, 255, 0], \
|
||||
[0, 255, 85], [0, 255, 170], [0, 255, 255], [0, 170, 255], [0, 85, 255], [0, 0, 255], [85, 0, 255], \
|
||||
[170, 0, 255], [255, 0, 255], [255, 0, 170], [255, 0, 85]]
|
||||
|
||||
for (k1_index, k2_index), color in zip(limbSeq, colors):
|
||||
keypoint1 = keypoints[k1_index - 1]
|
||||
keypoint2 = keypoints[k2_index - 1]
|
||||
|
||||
if keypoint1 is None or keypoint2 is None:
|
||||
continue
|
||||
|
||||
Y = np.array([keypoint1.x, keypoint2.x]) * float(W)
|
||||
X = np.array([keypoint1.y, keypoint2.y]) * float(H)
|
||||
mX = np.mean(X)
|
||||
mY = np.mean(Y)
|
||||
length = ((X[0] - X[1]) ** 2 + (Y[0] - Y[1]) ** 2) ** 0.5
|
||||
angle = math.degrees(math.atan2(X[0] - X[1], Y[0] - Y[1]))
|
||||
polygon = cv2.ellipse2Poly((int(mY), int(mX)), (int(length / 2), stickwidth), int(angle), 0, 360, 1)
|
||||
cv2.fillConvexPoly(canvas, polygon, [int(float(c) * 0.6) for c in color])
|
||||
|
||||
for keypoint, color in zip(keypoints, colors):
|
||||
if keypoint is None:
|
||||
continue
|
||||
|
||||
x, y = keypoint.x, keypoint.y
|
||||
x = int(x * W)
|
||||
y = int(y * H)
|
||||
cv2.circle(canvas, (int(x), int(y)), 4, color, thickness=-1)
|
||||
|
||||
return canvas
|
||||
|
||||
def draw_handpose(canvas: np.ndarray, keypoints) -> np.ndarray:
|
||||
"""
|
||||
Draw keypoints and connections representing hand pose on a given canvas.
|
||||
|
||||
Args:
|
||||
canvas (np.ndarray): A 3D numpy array representing the canvas (image) on which to draw the hand pose.
|
||||
keypoints (List[Keypoint]| None): A list of Keypoint objects representing the hand keypoints to be drawn
|
||||
or None if no keypoints are present.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 3D numpy array representing the modified canvas with the drawn hand pose.
|
||||
|
||||
Note:
|
||||
The function expects the x and y coordinates of the keypoints to be normalized between 0 and 1.
|
||||
"""
|
||||
if not keypoints:
|
||||
return canvas
|
||||
|
||||
if not is_normalized(keypoints):
|
||||
H, W = 1.0, 1.0
|
||||
else:
|
||||
H, W, _ = canvas.shape
|
||||
|
||||
edges = [[0, 1], [1, 2], [2, 3], [3, 4], [0, 5], [5, 6], [6, 7], [7, 8], [0, 9], [9, 10], \
|
||||
[10, 11], [11, 12], [0, 13], [13, 14], [14, 15], [15, 16], [0, 17], [17, 18], [18, 19], [19, 20]]
|
||||
|
||||
for ie, (e1, e2) in enumerate(edges):
|
||||
k1 = keypoints[e1]
|
||||
k2 = keypoints[e2]
|
||||
if k1 is None or k2 is None:
|
||||
continue
|
||||
|
||||
x1 = int(k1.x * W)
|
||||
y1 = int(k1.y * H)
|
||||
x2 = int(k2.x * W)
|
||||
y2 = int(k2.y * H)
|
||||
if x1 > eps and y1 > eps and x2 > eps and y2 > eps:
|
||||
cv2.line(canvas, (x1, y1), (x2, y2), matplotlib.colors.hsv_to_rgb([ie / float(len(edges)), 1.0, 1.0]) * 255, thickness=2)
|
||||
|
||||
for keypoint in keypoints:
|
||||
if keypoint is None:
|
||||
continue
|
||||
|
||||
x, y = keypoint.x, keypoint.y
|
||||
x = int(x * W)
|
||||
y = int(y * H)
|
||||
if x > eps and y > eps:
|
||||
cv2.circle(canvas, (x, y), 4, (0, 0, 255), thickness=-1)
|
||||
return canvas
|
||||
|
||||
|
||||
def draw_facepose(canvas: np.ndarray, keypoints) -> np.ndarray:
|
||||
"""
|
||||
Draw keypoints representing face pose on a given canvas.
|
||||
|
||||
Args:
|
||||
canvas (np.ndarray): A 3D numpy array representing the canvas (image) on which to draw the face pose.
|
||||
keypoints (List[Keypoint]| None): A list of Keypoint objects representing the face keypoints to be drawn
|
||||
or None if no keypoints are present.
|
||||
|
||||
Returns:
|
||||
np.ndarray: A 3D numpy array representing the modified canvas with the drawn face pose.
|
||||
|
||||
Note:
|
||||
The function expects the x and y coordinates of the keypoints to be normalized between 0 and 1.
|
||||
"""
|
||||
if not keypoints:
|
||||
return canvas
|
||||
|
||||
if not is_normalized(keypoints):
|
||||
H, W = 1.0, 1.0
|
||||
else:
|
||||
H, W, _ = canvas.shape
|
||||
|
||||
for keypoint in keypoints:
|
||||
if keypoint is None:
|
||||
continue
|
||||
|
||||
x, y = keypoint.x, keypoint.y
|
||||
x = int(x * W)
|
||||
y = int(y * H)
|
||||
if x > eps and y > eps:
|
||||
cv2.circle(canvas, (x, y), 3, (255, 255, 255), thickness=-1)
|
||||
return canvas
|
||||
|
||||
# detect hand according to body pose keypoints
|
||||
# please refer to https://github.com/CMU-Perceptual-Computing-Lab/openpose/blob/master/src/openpose/hand/handDetector.cpp
|
||||
def handDetect(candidate, subset, oriImg):
|
||||
# right hand: wrist 4, elbow 3, shoulder 2
|
||||
# left hand: wrist 7, elbow 6, shoulder 5
|
||||
ratioWristElbow = 0.33
|
||||
detect_result = []
|
||||
image_height, image_width = oriImg.shape[0:2]
|
||||
for person in subset.astype(int):
|
||||
# if any of three not detected
|
||||
has_left = np.sum(person[[5, 6, 7]] == -1) == 0
|
||||
has_right = np.sum(person[[2, 3, 4]] == -1) == 0
|
||||
if not (has_left or has_right):
|
||||
continue
|
||||
hands = []
|
||||
#left hand
|
||||
if has_left:
|
||||
left_shoulder_index, left_elbow_index, left_wrist_index = person[[5, 6, 7]]
|
||||
x1, y1 = candidate[left_shoulder_index][:2]
|
||||
x2, y2 = candidate[left_elbow_index][:2]
|
||||
x3, y3 = candidate[left_wrist_index][:2]
|
||||
hands.append([x1, y1, x2, y2, x3, y3, True])
|
||||
# right hand
|
||||
if has_right:
|
||||
right_shoulder_index, right_elbow_index, right_wrist_index = person[[2, 3, 4]]
|
||||
x1, y1 = candidate[right_shoulder_index][:2]
|
||||
x2, y2 = candidate[right_elbow_index][:2]
|
||||
x3, y3 = candidate[right_wrist_index][:2]
|
||||
hands.append([x1, y1, x2, y2, x3, y3, False])
|
||||
|
||||
for x1, y1, x2, y2, x3, y3, is_left in hands:
|
||||
# pos_hand = pos_wrist + ratio * (pos_wrist - pos_elbox) = (1 + ratio) * pos_wrist - ratio * pos_elbox
|
||||
# handRectangle.x = posePtr[wrist*3] + ratioWristElbow * (posePtr[wrist*3] - posePtr[elbow*3]);
|
||||
# handRectangle.y = posePtr[wrist*3+1] + ratioWristElbow * (posePtr[wrist*3+1] - posePtr[elbow*3+1]);
|
||||
# const auto distanceWristElbow = getDistance(poseKeypoints, person, wrist, elbow);
|
||||
# const auto distanceElbowShoulder = getDistance(poseKeypoints, person, elbow, shoulder);
|
||||
# handRectangle.width = 1.5f * fastMax(distanceWristElbow, 0.9f * distanceElbowShoulder);
|
||||
x = x3 + ratioWristElbow * (x3 - x2)
|
||||
y = y3 + ratioWristElbow * (y3 - y2)
|
||||
distanceWristElbow = math.sqrt((x3 - x2) ** 2 + (y3 - y2) ** 2)
|
||||
distanceElbowShoulder = math.sqrt((x2 - x1) ** 2 + (y2 - y1) ** 2)
|
||||
width = 1.5 * max(distanceWristElbow, 0.9 * distanceElbowShoulder)
|
||||
# x-y refers to the center --> offset to topLeft point
|
||||
# handRectangle.x -= handRectangle.width / 2.f;
|
||||
# handRectangle.y -= handRectangle.height / 2.f;
|
||||
x -= width / 2
|
||||
y -= width / 2 # width = height
|
||||
# overflow the image
|
||||
if x < 0: x = 0
|
||||
if y < 0: y = 0
|
||||
width1 = width
|
||||
width2 = width
|
||||
if x + width > image_width: width1 = image_width - x
|
||||
if y + width > image_height: width2 = image_height - y
|
||||
width = min(width1, width2)
|
||||
# the max hand box value is 20 pixels
|
||||
if width >= 20:
|
||||
detect_result.append([int(x), int(y), int(width), is_left])
|
||||
|
||||
'''
|
||||
return value: [[x, y, w, True if left hand else False]].
|
||||
width=height since the network require squared input.
|
||||
x, y is the coordinate of top left
|
||||
'''
|
||||
return detect_result
|
||||
|
||||
# Written by Lvmin
|
||||
def faceDetect(candidate, subset, oriImg):
|
||||
# left right eye ear 14 15 16 17
|
||||
detect_result = []
|
||||
image_height, image_width = oriImg.shape[0:2]
|
||||
for person in subset.astype(int):
|
||||
has_head = person[0] > -1
|
||||
if not has_head:
|
||||
continue
|
||||
|
||||
has_left_eye = person[14] > -1
|
||||
has_right_eye = person[15] > -1
|
||||
has_left_ear = person[16] > -1
|
||||
has_right_ear = person[17] > -1
|
||||
|
||||
if not (has_left_eye or has_right_eye or has_left_ear or has_right_ear):
|
||||
continue
|
||||
|
||||
head, left_eye, right_eye, left_ear, right_ear = person[[0, 14, 15, 16, 17]]
|
||||
|
||||
width = 0.0
|
||||
x0, y0 = candidate[head][:2]
|
||||
|
||||
if has_left_eye:
|
||||
x1, y1 = candidate[left_eye][:2]
|
||||
d = max(abs(x0 - x1), abs(y0 - y1))
|
||||
width = max(width, d * 3.0)
|
||||
|
||||
if has_right_eye:
|
||||
x1, y1 = candidate[right_eye][:2]
|
||||
d = max(abs(x0 - x1), abs(y0 - y1))
|
||||
width = max(width, d * 3.0)
|
||||
|
||||
if has_left_ear:
|
||||
x1, y1 = candidate[left_ear][:2]
|
||||
d = max(abs(x0 - x1), abs(y0 - y1))
|
||||
width = max(width, d * 1.5)
|
||||
|
||||
if has_right_ear:
|
||||
x1, y1 = candidate[right_ear][:2]
|
||||
d = max(abs(x0 - x1), abs(y0 - y1))
|
||||
width = max(width, d * 1.5)
|
||||
|
||||
x, y = x0, y0
|
||||
|
||||
x -= width
|
||||
y -= width
|
||||
|
||||
if x < 0:
|
||||
x = 0
|
||||
|
||||
if y < 0:
|
||||
y = 0
|
||||
|
||||
width1 = width * 2
|
||||
width2 = width * 2
|
||||
|
||||
if x + width > image_width:
|
||||
width1 = image_width - x
|
||||
|
||||
if y + width > image_height:
|
||||
width2 = image_height - y
|
||||
|
||||
width = min(width1, width2)
|
||||
|
||||
if width >= 20:
|
||||
detect_result.append([int(x), int(y), int(width)])
|
||||
|
||||
return detect_result
|
||||
|
||||
# get max index of 2d array
|
||||
def npmax(array):
|
||||
arrayindex = array.argmax(1)
|
||||
arrayvalue = array.max(1)
|
||||
i = arrayvalue.argmax()
|
||||
j = arrayindex[i]
|
||||
return i, j
|
||||
@@ -0,0 +1,130 @@
|
||||
from typing import List, NamedTuple, Optional, Union
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import onnxruntime as ort
|
||||
|
||||
from .onnxdet import inference_detector
|
||||
from .onnxpose import inference_pose
|
||||
|
||||
|
||||
class Keypoint(NamedTuple):
|
||||
x: float
|
||||
y: float
|
||||
score: float = 1.0
|
||||
id: int = -1
|
||||
|
||||
|
||||
class BodyResult(NamedTuple):
|
||||
# Note: Using `Optional` instead of `|` operator as the ladder is a Python
|
||||
# 3.10 feature.
|
||||
# Annotator code should be Python 3.8 Compatible, as controlnet repo uses
|
||||
# Python 3.8 environment.
|
||||
# https://github.com/lllyasviel/ControlNet/blob/d3284fcd0972c510635a4f5abe2eeb71dc0de524/environment.yaml#L6
|
||||
keypoints: List[Optional[Keypoint]]
|
||||
total_score: float = 0.0
|
||||
total_parts: int = 0
|
||||
|
||||
|
||||
HandResult = List[Keypoint]
|
||||
FaceResult = List[Keypoint]
|
||||
AnimalPoseResult = List[Keypoint]
|
||||
|
||||
|
||||
class HumanPoseResult(NamedTuple):
|
||||
body: BodyResult
|
||||
left_hand: Optional[HandResult]
|
||||
right_hand: Optional[HandResult]
|
||||
face: Optional[FaceResult]
|
||||
|
||||
|
||||
class Wholebody:
|
||||
def __init__(self, onnx_det: str, onnx_pose: str):
|
||||
# Always loads to CPU to avoid building OpenCV.
|
||||
device = 'cpu'
|
||||
backend = cv2.dnn.DNN_BACKEND_OPENCV if device == 'cpu' else cv2.dnn.DNN_BACKEND_CUDA
|
||||
# You need to manually build OpenCV through cmake to work with your GPU.
|
||||
providers = cv2.dnn.DNN_TARGET_CPU if device == 'cpu' else cv2.dnn.DNN_TARGET_CUDA
|
||||
|
||||
self.session_det = cv2.dnn.readNetFromONNX(onnx_det)
|
||||
self.session_det.setPreferableBackend(backend)
|
||||
self.session_det.setPreferableTarget(providers)
|
||||
|
||||
self.session_pose = cv2.dnn.readNetFromONNX(onnx_pose)
|
||||
self.session_pose.setPreferableBackend(backend)
|
||||
self.session_pose.setPreferableTarget(providers)
|
||||
|
||||
def __call__(self, oriImg):
|
||||
det_result = inference_detector(self.session_det, oriImg)
|
||||
if det_result is None:
|
||||
return None
|
||||
|
||||
keypoints, scores = inference_pose(self.session_pose, det_result, oriImg)
|
||||
|
||||
keypoints_info = np.concatenate(
|
||||
(keypoints, scores[..., None]), axis=-1)
|
||||
# compute neck joint
|
||||
neck = np.mean(keypoints_info[:, [5, 6]], axis=1)
|
||||
# neck score when visualizing pred
|
||||
neck[:, 2:4] = np.logical_and(
|
||||
keypoints_info[:, 5, 2:4] > 0.3,
|
||||
keypoints_info[:, 6, 2:4] > 0.3).astype(int)
|
||||
new_keypoints_info = np.insert(
|
||||
keypoints_info, 17, neck, axis=1)
|
||||
mmpose_idx = [
|
||||
17, 6, 8, 10, 7, 9, 12, 14, 16, 13, 15, 2, 1, 4, 3
|
||||
]
|
||||
openpose_idx = [
|
||||
1, 2, 3, 4, 6, 7, 8, 9, 10, 12, 13, 14, 15, 16, 17
|
||||
]
|
||||
new_keypoints_info[:, openpose_idx] = \
|
||||
new_keypoints_info[:, mmpose_idx]
|
||||
keypoints_info = new_keypoints_info
|
||||
|
||||
return keypoints_info
|
||||
|
||||
@staticmethod
|
||||
def format_result(keypoints_info: Optional[np.ndarray]) -> List[HumanPoseResult]:
|
||||
def format_keypoint_part(
|
||||
part: np.ndarray,
|
||||
) -> Optional[List[Optional[Keypoint]]]:
|
||||
keypoints = [
|
||||
Keypoint(x, y, score, i) if score >= 0.3 else None
|
||||
for i, (x, y, score) in enumerate(part)
|
||||
]
|
||||
return (
|
||||
None if all(keypoint is None for keypoint in keypoints) else keypoints
|
||||
)
|
||||
|
||||
def total_score(keypoints: Optional[List[Optional[Keypoint]]]) -> float:
|
||||
return (
|
||||
sum(keypoint.score for keypoint in keypoints if keypoint is not None)
|
||||
if keypoints is not None
|
||||
else 0.0
|
||||
)
|
||||
|
||||
pose_results = []
|
||||
if keypoints_info is None:
|
||||
return pose_results
|
||||
|
||||
for instance in keypoints_info:
|
||||
body_keypoints = format_keypoint_part(instance[:18]) or ([None] * 18)
|
||||
left_hand = format_keypoint_part(instance[92:113])
|
||||
right_hand = format_keypoint_part(instance[113:134])
|
||||
face = format_keypoint_part(instance[24:92])
|
||||
|
||||
# Openpose face consists of 70 points in total, while DWPose only
|
||||
# provides 68 points. Padding the last 2 points.
|
||||
if face is not None:
|
||||
# left eye
|
||||
face.append(body_keypoints[14])
|
||||
# right eye
|
||||
face.append(body_keypoints[15])
|
||||
|
||||
body = BodyResult(
|
||||
body_keypoints, total_score(body_keypoints), len(body_keypoints)
|
||||
)
|
||||
pose_results.append(HumanPoseResult(body, left_hand, right_hand, face))
|
||||
|
||||
return pose_results
|
||||
|
||||
@@ -0,0 +1,514 @@
|
||||
# This folder is modified from the https://github.com/Mikubill/sd-webui-controlnet
|
||||
import os
|
||||
|
||||
import cv2
|
||||
import folder_paths
|
||||
import numpy as np
|
||||
import torch
|
||||
from einops import rearrange
|
||||
|
||||
from .dwpose_utils import DWposeDetector
|
||||
from .zoe.zoedepth.models.zoedepth.zoedepth_v1 import ZoeDepth
|
||||
from .zoe.zoedepth.utils.config import get_config
|
||||
|
||||
remote_onnx_det = "https://huggingface.co/yzd-v/DWPose/resolve/main/yolox_l.onnx"
|
||||
remote_onnx_pose = "https://huggingface.co/yzd-v/DWPose/resolve/main/dw-ll_ucoco_384.onnx"
|
||||
remote_zoe= "https://huggingface.co/lllyasviel/Annotators/resolve/main/ZoeD_M12_N.pt"
|
||||
|
||||
def read_video(video_path):
|
||||
cap = cv2.VideoCapture(video_path)
|
||||
frames = []
|
||||
while cap.isOpened():
|
||||
ret, frame = cap.read()
|
||||
if not ret:
|
||||
break
|
||||
frame = cv2.cvtColor(frame, cv2.COLOR_RGB2BGR)
|
||||
frames.append(frame)
|
||||
cap.release()
|
||||
return frames
|
||||
|
||||
def HWC3(x):
|
||||
assert x.dtype == np.uint8
|
||||
if x.ndim == 2:
|
||||
x = x[:, :, None]
|
||||
assert x.ndim == 3
|
||||
H, W, C = x.shape
|
||||
assert C == 1 or C == 3 or C == 4
|
||||
if C == 3:
|
||||
return x
|
||||
if C == 1:
|
||||
return np.concatenate([x, x, x], axis=2)
|
||||
if C == 4:
|
||||
color = x[:, :, 0:3].astype(np.float32)
|
||||
alpha = x[:, :, 3:4].astype(np.float32) / 255.0
|
||||
y = color * alpha + 255.0 * (1.0 - alpha)
|
||||
y = y.clip(0, 255).astype(np.uint8)
|
||||
return y
|
||||
|
||||
def pad64(x):
|
||||
return int(np.ceil(float(x) / 64.0) * 64 - x)
|
||||
|
||||
def safer_memory(x):
|
||||
# Fix many MAC/AMD problems
|
||||
return np.ascontiguousarray(x.copy()).copy()
|
||||
|
||||
def resize_image_with_pad(input_image, resolution, skip_hwc3=False):
|
||||
if skip_hwc3:
|
||||
img = input_image
|
||||
else:
|
||||
img = HWC3(input_image)
|
||||
H_raw, W_raw, _ = img.shape
|
||||
k = float(resolution) / float(min(H_raw, W_raw))
|
||||
interpolation = cv2.INTER_CUBIC if k > 1 else cv2.INTER_AREA
|
||||
H_target = int(np.round(float(H_raw) * k))
|
||||
W_target = int(np.round(float(W_raw) * k))
|
||||
img = cv2.resize(img, (W_target, H_target), interpolation=interpolation)
|
||||
H_pad, W_pad = pad64(H_target), pad64(W_target)
|
||||
img_padded = np.pad(img, [[0, H_pad], [0, W_pad], [0, 0]], mode='edge')
|
||||
|
||||
def remove_pad(x):
|
||||
return safer_memory(x[:H_target, :W_target])
|
||||
|
||||
return safer_memory(img_padded), remove_pad
|
||||
|
||||
def load_file_from_url(
|
||||
url: str,
|
||||
model_dir: str,
|
||||
progress: bool = True,
|
||||
file_name: str | None = None,
|
||||
hash_prefix: str | None = None,
|
||||
) -> str:
|
||||
"""Download a file from `url` into `model_dir`, using the file present if possible.
|
||||
|
||||
Returns the path to the downloaded file.
|
||||
"""
|
||||
from urllib.parse import urlparse
|
||||
os.makedirs(model_dir, exist_ok=True)
|
||||
if not file_name:
|
||||
parts = urlparse(url)
|
||||
file_name = os.path.basename(parts.path)
|
||||
cached_file = os.path.abspath(os.path.join(model_dir, file_name))
|
||||
if not os.path.exists(cached_file):
|
||||
print(f'Downloading: "{url}" to {cached_file}\n')
|
||||
from torch.hub import download_url_to_file
|
||||
download_url_to_file(url, cached_file, progress=progress, hash_prefix=hash_prefix)
|
||||
return cached_file
|
||||
|
||||
class VideoToCanny:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"input_video": ("IMAGE",),
|
||||
"low_threshold": ("INT", {"default": 100, "min": 0, "max": 255, "step": 1}),
|
||||
"high_threshold": ("INT", {"default": 200, "min": 0, "max": 255, "step": 1}),
|
||||
"video_length": (
|
||||
"INT", {"default": 81, "min": 1, "max": 81, "step": 4}
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES =("images",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "CogVideoXFUNWrapper"
|
||||
|
||||
def process(self, input_video, low_threshold, high_threshold, video_length):
|
||||
def extract_canny_frames(frames):
|
||||
canny_frames = []
|
||||
for frame in frames:
|
||||
gray = cv2.cvtColor(frame, cv2.COLOR_RGB2GRAY)
|
||||
edges = cv2.Canny(gray, low_threshold, high_threshold)
|
||||
edges_colored = cv2.cvtColor(edges, cv2.COLOR_GRAY2RGB)
|
||||
canny_frames.append(edges_colored)
|
||||
return canny_frames
|
||||
|
||||
if type(input_video) is str:
|
||||
video_frames = read_video(input_video)
|
||||
else:
|
||||
video_frames = np.array(input_video * 255, np.uint8)[:video_length]
|
||||
output_video = extract_canny_frames(video_frames)
|
||||
output_video = torch.from_numpy(np.array(output_video)) / 255
|
||||
return (output_video,)
|
||||
|
||||
class VideoToDepth:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"input_video": ("IMAGE",),
|
||||
"video_length": (
|
||||
"INT", {"default": 81, "min": 1, "max": 81, "step": 4}
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES = ("images",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "CogVideoXFUNWrapper"
|
||||
|
||||
|
||||
def process_frame(self, model, image, device, weight_dtype):
|
||||
with torch.no_grad():
|
||||
image, remove_pad = resize_image_with_pad(image, 512)
|
||||
image_depth = image
|
||||
with torch.no_grad():
|
||||
image_depth = torch.from_numpy(image_depth).to(device, weight_dtype)
|
||||
image_depth = image_depth / 255.0
|
||||
image_depth = rearrange(image_depth, 'h w c -> 1 c h w')
|
||||
depth = model.infer(image_depth)
|
||||
|
||||
depth = depth[0, 0].cpu().numpy()
|
||||
|
||||
vmin = np.percentile(depth, 2)
|
||||
vmax = np.percentile(depth, 85)
|
||||
|
||||
depth -= vmin
|
||||
depth /= vmax - vmin
|
||||
depth = 1.0 - depth
|
||||
depth_image = (depth * 255.0).clip(0, 255).astype(np.uint8)
|
||||
image = remove_pad(depth_image)
|
||||
image = HWC3(image)
|
||||
return image
|
||||
|
||||
def process(self, input_video, video_length):
|
||||
model = ZoeDepth.build_from_config(get_config("zoedepth", "infer"))
|
||||
|
||||
# Detect model is existing or not
|
||||
possible_folders = ["CogVideoX_Fun/Third_Party", "Fun_Models/Third_Party", "VideoX_Fun/Third_Party"] # Possible folder names to check
|
||||
|
||||
# Check if the model exists in any of the possible folders within folder_paths.models_dir
|
||||
zoe_model_path = "ZoeD_M12_N.pt"
|
||||
for folder in possible_folders:
|
||||
candidate_path = os.path.join(folder_paths.models_dir, folder, zoe_model_path)
|
||||
if os.path.exists(candidate_path):
|
||||
zoe_model_path = candidate_path
|
||||
break
|
||||
if not os.path.exists(zoe_model_path):
|
||||
load_file_from_url(remote_zoe, model_dir=os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
|
||||
zoe_model_path = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", zoe_model_path)
|
||||
|
||||
model.load_state_dict(
|
||||
torch.load(zoe_model_path, map_location="cpu")['model'],
|
||||
strict=False
|
||||
)
|
||||
if torch.cuda.is_available():
|
||||
device = "cuda"
|
||||
weight_dtype = torch.float32
|
||||
else:
|
||||
device = "cpu"
|
||||
weight_dtype = torch.float32
|
||||
model = model.to(device=device, dtype=weight_dtype).eval().requires_grad_(False)
|
||||
|
||||
if isinstance(input_video, str):
|
||||
video_frames = read_video(input_video)
|
||||
else:
|
||||
video_frames = np.array(input_video * 255, np.uint8)[:video_length]
|
||||
|
||||
output_video = [self.process_frame(model, frame, device, weight_dtype) for frame in video_frames]
|
||||
output_video = torch.from_numpy(np.array(output_video)) / 255
|
||||
|
||||
return (output_video,)
|
||||
|
||||
|
||||
class VideoToPose:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"input_video": ("IMAGE",),
|
||||
"video_length": (
|
||||
"INT", {"default": 81, "min": 1, "max": 81, "step": 4}
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES = ("images",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "CogVideoXFUNWrapper"
|
||||
|
||||
def process_frame(self, model, image):
|
||||
with torch.no_grad():
|
||||
image, remove_pad = resize_image_with_pad(image, 512)
|
||||
pose_image = model(image)
|
||||
image = remove_pad(pose_image)
|
||||
image = HWC3(image)
|
||||
return image
|
||||
|
||||
def process(self, input_video, video_length):
|
||||
# Detect model is existing or not
|
||||
possible_folders = ["CogVideoX_Fun/Third_Party", "Fun_Models/Third_Party", "VideoX_Fun/Third_Party"] # Possible folder names to check
|
||||
|
||||
# Check if the model exists in any of the possible folders within folder_paths.models_dir
|
||||
onnx_det = "yolox_l.onnx"
|
||||
for folder in possible_folders:
|
||||
candidate_path = os.path.join(folder_paths.models_dir, folder, onnx_det)
|
||||
if os.path.exists(candidate_path):
|
||||
onnx_det = candidate_path
|
||||
break
|
||||
if not os.path.exists(onnx_det):
|
||||
load_file_from_url(remote_onnx_det, os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
|
||||
onnx_det = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", onnx_det)
|
||||
|
||||
onnx_pose = "dw-ll_ucoco_384.onnx"
|
||||
for folder in possible_folders:
|
||||
candidate_path = os.path.join(folder_paths.models_dir, folder, onnx_pose)
|
||||
if os.path.exists(candidate_path):
|
||||
onnx_pose = candidate_path
|
||||
break
|
||||
if not os.path.exists(onnx_pose):
|
||||
load_file_from_url(remote_onnx_pose, os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
|
||||
onnx_pose = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", onnx_pose)
|
||||
|
||||
model = DWposeDetector(onnx_det, onnx_pose)
|
||||
|
||||
if isinstance(input_video, str):
|
||||
video_frames = read_video(input_video)
|
||||
else:
|
||||
video_frames = np.array(input_video * 255, np.uint8)[:video_length]
|
||||
|
||||
output_video = [self.process_frame(model, frame) for frame in video_frames]
|
||||
output_video = torch.from_numpy(np.array(output_video)) / 255
|
||||
return (output_video,)
|
||||
|
||||
|
||||
class ImageToCanny:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"input_image": ("IMAGE",),
|
||||
"low_threshold": ("INT", {"default": 100, "min": 0, "max": 255, "step": 1}),
|
||||
"high_threshold": ("INT", {"default": 200, "min": 0, "max": 255, "step": 1}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES = ("image",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "CogVideoXFUNWrapper"
|
||||
|
||||
def process(self, input_image, low_threshold, high_threshold):
|
||||
# Convert input image to numpy array
|
||||
image = np.array(input_image * 255, np.uint8)
|
||||
|
||||
# If it's a batch of images, only process the first one
|
||||
if len(image.shape) == 4:
|
||||
image = image[0]
|
||||
|
||||
# Convert to grayscale
|
||||
gray = cv2.cvtColor(image, cv2.COLOR_RGB2GRAY)
|
||||
|
||||
# Canny edge detection
|
||||
edges = cv2.Canny(gray, low_threshold, high_threshold)
|
||||
|
||||
# Convert back to RGB format
|
||||
edges_colored = cv2.cvtColor(edges, cv2.COLOR_GRAY2RGB)
|
||||
|
||||
# Convert to torch tensor and normalize
|
||||
output_image = torch.from_numpy(edges_colored).float() / 255.0
|
||||
|
||||
# Add batch dimension
|
||||
output_image = output_image.unsqueeze(0)
|
||||
|
||||
return (output_image,)
|
||||
|
||||
|
||||
class ImageToDepth:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"input_image": ("IMAGE",),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES = ("image",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "CogVideoXFUNWrapper"
|
||||
|
||||
def process_single_image(self, model, image, device, weight_dtype):
|
||||
"""
|
||||
Process a single image to generate depth map
|
||||
|
||||
Args:
|
||||
model: ZoeDepth model instance
|
||||
image: Input image as numpy array
|
||||
device: Computing device (cuda/cpu)
|
||||
weight_dtype: Data type for model weights
|
||||
|
||||
Returns:
|
||||
Processed depth map as numpy array
|
||||
"""
|
||||
with torch.no_grad():
|
||||
# Resize image with padding to match model input size
|
||||
image, remove_pad = resize_image_with_pad(image, 512)
|
||||
image_depth = image
|
||||
|
||||
with torch.no_grad():
|
||||
# Convert to tensor and normalize
|
||||
image_depth = torch.from_numpy(image_depth).to(device, weight_dtype)
|
||||
image_depth = image_depth / 255.0
|
||||
# Rearrange dimensions for model input
|
||||
image_depth = rearrange(image_depth, 'h w c -> 1 c h w')
|
||||
# Infer depth map
|
||||
depth = model.infer(image_depth)
|
||||
|
||||
depth = depth[0, 0].cpu().numpy()
|
||||
|
||||
# Normalize depth values using percentiles
|
||||
vmin = np.percentile(depth, 2)
|
||||
vmax = np.percentile(depth, 85)
|
||||
|
||||
depth -= vmin
|
||||
depth /= vmax - vmin
|
||||
depth = 1.0 - depth
|
||||
# Convert to uint8 format
|
||||
depth_image = (depth * 255.0).clip(0, 255).astype(np.uint8)
|
||||
|
||||
# Remove padding and ensure 3-channel output
|
||||
image = remove_pad(depth_image)
|
||||
image = HWC3(image)
|
||||
return image
|
||||
|
||||
def process(self, input_image):
|
||||
# Initialize ZoeDepth model
|
||||
model = ZoeDepth.build_from_config(get_config("zoedepth", "infer"))
|
||||
|
||||
# Detect model path from possible folders
|
||||
possible_folders = ["CogVideoX_Fun/Third_Party", "Fun_Models/Third_Party", "VideoX_Fun/Third_Party"]
|
||||
zoe_model_path = "ZoeD_M12_N.pt"
|
||||
|
||||
# Search for existing model file
|
||||
for folder in possible_folders:
|
||||
candidate_path = os.path.join(folder_paths.models_dir, folder, zoe_model_path)
|
||||
if os.path.exists(candidate_path):
|
||||
zoe_model_path = candidate_path
|
||||
break
|
||||
|
||||
# Download model if not found locally
|
||||
if not os.path.exists(zoe_model_path):
|
||||
load_file_from_url(remote_zoe, model_dir=os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
|
||||
zoe_model_path = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", zoe_model_path)
|
||||
|
||||
# Load model weights
|
||||
model.load_state_dict(
|
||||
torch.load(zoe_model_path, map_location="cpu")['model'],
|
||||
strict=False
|
||||
)
|
||||
|
||||
# Set device and data type
|
||||
if torch.cuda.is_available():
|
||||
device = "cuda"
|
||||
weight_dtype = torch.float32
|
||||
else:
|
||||
device = "cpu"
|
||||
weight_dtype = torch.float32
|
||||
|
||||
# Move model to device and set to evaluation mode
|
||||
model = model.to(device=device, dtype=weight_dtype).eval().requires_grad_(False)
|
||||
|
||||
# Convert input image to numpy array
|
||||
image = np.array(input_image * 255, np.uint8)
|
||||
|
||||
# If it's a batch of images, only process the first one
|
||||
if len(image.shape) == 4:
|
||||
image = image[0]
|
||||
|
||||
# Process image to generate depth map
|
||||
output_image = self.process_single_image(model, image, device, weight_dtype)
|
||||
output_image = torch.from_numpy(output_image).float() / 255.0
|
||||
|
||||
# Add batch dimension
|
||||
output_image = output_image.unsqueeze(0)
|
||||
|
||||
return (output_image,)
|
||||
|
||||
|
||||
class ImageToPose:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"input_image": ("IMAGE",),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE",)
|
||||
RETURN_NAMES = ("image",)
|
||||
FUNCTION = "process"
|
||||
CATEGORY = "CogVideoXFUNWrapper"
|
||||
|
||||
def process_single_image(self, model, image):
|
||||
"""
|
||||
Process a single image to detect and draw pose keypoints
|
||||
|
||||
Args:
|
||||
model: DWPose detector model instance
|
||||
image: Input image as numpy array
|
||||
|
||||
Returns:
|
||||
Image with pose keypoints drawn as numpy array
|
||||
"""
|
||||
with torch.no_grad():
|
||||
# Resize image with padding to match model input size
|
||||
image, remove_pad = resize_image_with_pad(image, 512)
|
||||
# Detect and draw pose keypoints
|
||||
pose_image = model(image)
|
||||
# Remove padding
|
||||
image = remove_pad(pose_image)
|
||||
# Ensure 3-channel output
|
||||
image = HWC3(image)
|
||||
return image
|
||||
|
||||
def process(self, input_image):
|
||||
# Detect model paths from possible folders
|
||||
possible_folders = ["CogVideoX_Fun/Third_Party", "Fun_Models/Third_Party", "VideoX_Fun/Third_Party"]
|
||||
|
||||
# Search for detection model (yolox_l.onnx)
|
||||
onnx_det = "yolox_l.onnx"
|
||||
for folder in possible_folders:
|
||||
candidate_path = os.path.join(folder_paths.models_dir, folder, onnx_det)
|
||||
if os.path.exists(candidate_path):
|
||||
onnx_det = candidate_path
|
||||
break
|
||||
|
||||
# Download detection model if not found locally
|
||||
if not os.path.exists(onnx_det):
|
||||
load_file_from_url(remote_onnx_det, os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
|
||||
onnx_det = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", onnx_det)
|
||||
|
||||
# Search for pose model (dw-ll_ucoco_384.onnx)
|
||||
onnx_pose = "dw-ll_ucoco_384.onnx"
|
||||
for folder in possible_folders:
|
||||
candidate_path = os.path.join(folder_paths.models_dir, folder, onnx_pose)
|
||||
if os.path.exists(candidate_path):
|
||||
onnx_pose = candidate_path
|
||||
break
|
||||
|
||||
# Download pose model if not found locally
|
||||
if not os.path.exists(onnx_pose):
|
||||
load_file_from_url(remote_onnx_pose, os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party"))
|
||||
onnx_pose = os.path.join(folder_paths.models_dir, "Fun_Models/Third_Party", onnx_pose)
|
||||
|
||||
# Initialize DWPose detector model
|
||||
model = DWposeDetector(onnx_det, onnx_pose)
|
||||
|
||||
# Convert input image to numpy array
|
||||
image = np.array(input_image * 255, np.uint8)
|
||||
|
||||
# If it's a batch of images, only process the first one
|
||||
if len(image.shape) == 4:
|
||||
image = image[0]
|
||||
|
||||
# Process image to detect and draw pose
|
||||
output_image = self.process_single_image(model, image)
|
||||
output_image = torch.from_numpy(output_image).float() / 255.0
|
||||
|
||||
# Add batch dimension for compatibility
|
||||
output_image = output_image.unsqueeze(0)
|
||||
|
||||
return (output_image,)
|
||||
@@ -0,0 +1,21 @@
|
||||
MIT License
|
||||
|
||||
Copyright (c) 2022 Intelligent Systems Lab Org
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
of this software and associated documentation files (the "Software"), to deal
|
||||
in the Software without restriction, including without limitation the rights
|
||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
copies of the Software, and to permit persons to whom the Software is
|
||||
furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all
|
||||
copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
SOFTWARE.
|
||||
@@ -0,0 +1,41 @@
|
||||
# This folder is modified from the https://github.com/Mikubill/sd-webui-controlnet
|
||||
import os
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import torch
|
||||
from einops import rearrange
|
||||
from torch import nn
|
||||
|
||||
from .zoedepth.models.zoedepth.zoedepth_v1 import ZoeDepth
|
||||
from .zoedepth.utils.config import get_config
|
||||
|
||||
|
||||
class ZoeDetector(nn.Module):
|
||||
def __init__(self, model_path):
|
||||
conf = get_config("zoedepth", "infer")
|
||||
model = ZoeDepth.build_from_config(conf)
|
||||
model.load_state_dict(torch.load(model_path, map_location=model.device)['model'])
|
||||
model.eval()
|
||||
self.model = model
|
||||
|
||||
def __call__(self, input_image):
|
||||
assert input_image.ndim == 3
|
||||
image_depth = input_image
|
||||
with torch.no_grad():
|
||||
image_depth = torch.from_numpy(image_depth).float()
|
||||
image_depth = image_depth / 255.0
|
||||
image_depth = rearrange(image_depth, 'h w c -> 1 c h w')
|
||||
depth = self.model.infer(image_depth)
|
||||
|
||||
depth = depth[0, 0].cpu().numpy()
|
||||
|
||||
vmin = np.percentile(depth, 2)
|
||||
vmax = np.percentile(depth, 85)
|
||||
|
||||
depth -= vmin
|
||||
depth /= vmax - vmin
|
||||
depth = 1.0 - depth
|
||||
depth_image = (depth * 255.0).clip(0, 255).astype(np.uint8)
|
||||
|
||||
return depth_image
|
||||
@@ -0,0 +1,24 @@
|
||||
# MIT License
|
||||
|
||||
# Copyright (c) 2022 Intelligent Systems Lab Org
|
||||
|
||||
# Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
# of this software and associated documentation files (the "Software"), to deal
|
||||
# in the Software without restriction, including without limitation the rights
|
||||
# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
# copies of the Software, and to permit persons to whom the Software is
|
||||
# furnished to do so, subject to the following conditions:
|
||||
|
||||
# The above copyright notice and this permission notice shall be included in all
|
||||
# copies or substantial portions of the Software.
|
||||
|
||||
# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
# SOFTWARE.
|
||||
|
||||
# File author: Shariq Farooq Bhat
|
||||
|
||||
@@ -0,0 +1,380 @@
|
||||
# MIT License
|
||||
import os
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from torchvision.transforms import Normalize
|
||||
|
||||
# Copyright (c) 2022 Intelligent Systems Lab Org
|
||||
|
||||
# Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
# of this software and associated documentation files (the "Software"), to deal
|
||||
# in the Software without restriction, including without limitation the rights
|
||||
# to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
# copies of the Software, and to permit persons to whom the Software is
|
||||
# furnished to do so, subject to the following conditions:
|
||||
|
||||
# The above copyright notice and this permission notice shall be included in all
|
||||
# copies or substantial portions of the Software.
|
||||
|
||||
# THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
# IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
# FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
# AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
# LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
# OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
# SOFTWARE.
|
||||
|
||||
# File author: Shariq Farooq Bhat
|
||||
|
||||
|
||||
|
||||
def denormalize(x):
|
||||
"""Reverses the imagenet normalization applied to the input.
|
||||
|
||||
Args:
|
||||
x (torch.Tensor - shape(N,3,H,W)): input tensor
|
||||
|
||||
Returns:
|
||||
torch.Tensor - shape(N,3,H,W): Denormalized input
|
||||
"""
|
||||
mean = torch.Tensor([0.485, 0.456, 0.406]).view(1, 3, 1, 1).to(x.device)
|
||||
std = torch.Tensor([0.229, 0.224, 0.225]).view(1, 3, 1, 1).to(x.device)
|
||||
return x * std + mean
|
||||
|
||||
def get_activation(name, bank):
|
||||
def hook(model, input, output):
|
||||
bank[name] = output
|
||||
return hook
|
||||
|
||||
|
||||
class Resize(object):
|
||||
"""Resize sample to given size (width, height).
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
width,
|
||||
height,
|
||||
resize_target=True,
|
||||
keep_aspect_ratio=False,
|
||||
ensure_multiple_of=1,
|
||||
resize_method="lower_bound",
|
||||
):
|
||||
"""Init.
|
||||
Args:
|
||||
width (int): desired output width
|
||||
height (int): desired output height
|
||||
resize_target (bool, optional):
|
||||
True: Resize the full sample (image, mask, target).
|
||||
False: Resize image only.
|
||||
Defaults to True.
|
||||
keep_aspect_ratio (bool, optional):
|
||||
True: Keep the aspect ratio of the input sample.
|
||||
Output sample might not have the given width and height, and
|
||||
resize behaviour depends on the parameter 'resize_method'.
|
||||
Defaults to False.
|
||||
ensure_multiple_of (int, optional):
|
||||
Output width and height is constrained to be multiple of this parameter.
|
||||
Defaults to 1.
|
||||
resize_method (str, optional):
|
||||
"lower_bound": Output will be at least as large as the given size.
|
||||
"upper_bound": Output will be at max as large as the given size. (Output size might be smaller than given size.)
|
||||
"minimal": Scale as least as possible. (Output size might be smaller than given size.)
|
||||
Defaults to "lower_bound".
|
||||
"""
|
||||
print("Params passed to Resize transform:")
|
||||
print("\twidth: ", width)
|
||||
print("\theight: ", height)
|
||||
print("\tresize_target: ", resize_target)
|
||||
print("\tkeep_aspect_ratio: ", keep_aspect_ratio)
|
||||
print("\tensure_multiple_of: ", ensure_multiple_of)
|
||||
print("\tresize_method: ", resize_method)
|
||||
|
||||
self.__width = width
|
||||
self.__height = height
|
||||
|
||||
self.__keep_aspect_ratio = keep_aspect_ratio
|
||||
self.__multiple_of = ensure_multiple_of
|
||||
self.__resize_method = resize_method
|
||||
|
||||
def constrain_to_multiple_of(self, x, min_val=0, max_val=None):
|
||||
y = (np.round(x / self.__multiple_of) * self.__multiple_of).astype(int)
|
||||
|
||||
if max_val is not None and y > max_val:
|
||||
y = (np.floor(x / self.__multiple_of)
|
||||
* self.__multiple_of).astype(int)
|
||||
|
||||
if y < min_val:
|
||||
y = (np.ceil(x / self.__multiple_of)
|
||||
* self.__multiple_of).astype(int)
|
||||
|
||||
return y
|
||||
|
||||
def get_size(self, width, height):
|
||||
# determine new height and width
|
||||
scale_height = self.__height / height
|
||||
scale_width = self.__width / width
|
||||
|
||||
if self.__keep_aspect_ratio:
|
||||
if self.__resize_method == "lower_bound":
|
||||
# scale such that output size is lower bound
|
||||
if scale_width > scale_height:
|
||||
# fit width
|
||||
scale_height = scale_width
|
||||
else:
|
||||
# fit height
|
||||
scale_width = scale_height
|
||||
elif self.__resize_method == "upper_bound":
|
||||
# scale such that output size is upper bound
|
||||
if scale_width < scale_height:
|
||||
# fit width
|
||||
scale_height = scale_width
|
||||
else:
|
||||
# fit height
|
||||
scale_width = scale_height
|
||||
elif self.__resize_method == "minimal":
|
||||
# scale as least as possbile
|
||||
if abs(1 - scale_width) < abs(1 - scale_height):
|
||||
# fit width
|
||||
scale_height = scale_width
|
||||
else:
|
||||
# fit height
|
||||
scale_width = scale_height
|
||||
else:
|
||||
raise ValueError(
|
||||
f"resize_method {self.__resize_method} not implemented"
|
||||
)
|
||||
|
||||
if self.__resize_method == "lower_bound":
|
||||
new_height = self.constrain_to_multiple_of(
|
||||
scale_height * height, min_val=self.__height
|
||||
)
|
||||
new_width = self.constrain_to_multiple_of(
|
||||
scale_width * width, min_val=self.__width
|
||||
)
|
||||
elif self.__resize_method == "upper_bound":
|
||||
new_height = self.constrain_to_multiple_of(
|
||||
scale_height * height, max_val=self.__height
|
||||
)
|
||||
new_width = self.constrain_to_multiple_of(
|
||||
scale_width * width, max_val=self.__width
|
||||
)
|
||||
elif self.__resize_method == "minimal":
|
||||
new_height = self.constrain_to_multiple_of(scale_height * height)
|
||||
new_width = self.constrain_to_multiple_of(scale_width * width)
|
||||
else:
|
||||
raise ValueError(
|
||||
f"resize_method {self.__resize_method} not implemented")
|
||||
|
||||
return (new_width, new_height)
|
||||
|
||||
def __call__(self, x):
|
||||
width, height = self.get_size(*x.shape[-2:][::-1])
|
||||
return nn.functional.interpolate(x, (int(height), int(width)), mode='bilinear', align_corners=True)
|
||||
|
||||
class PrepForMidas(object):
|
||||
def __init__(self, resize_mode="minimal", keep_aspect_ratio=True, img_size=384, do_resize=True):
|
||||
if isinstance(img_size, int):
|
||||
img_size = (img_size, img_size)
|
||||
net_h, net_w = img_size
|
||||
self.normalization = Normalize(
|
||||
mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
|
||||
self.resizer = Resize(net_w, net_h, keep_aspect_ratio=keep_aspect_ratio, ensure_multiple_of=32, resize_method=resize_mode) \
|
||||
if do_resize else nn.Identity()
|
||||
|
||||
def __call__(self, x):
|
||||
return self.normalization(self.resizer(x))
|
||||
|
||||
|
||||
class MidasCore(nn.Module):
|
||||
def __init__(self, midas, trainable=False, fetch_features=True, layer_names=('out_conv', 'l4_rn', 'r4', 'r3', 'r2', 'r1'), freeze_bn=False, keep_aspect_ratio=True,
|
||||
img_size=384, **kwargs):
|
||||
"""Midas Base model used for multi-scale feature extraction.
|
||||
|
||||
Args:
|
||||
midas (torch.nn.Module): Midas model.
|
||||
trainable (bool, optional): Train midas model. Defaults to False.
|
||||
fetch_features (bool, optional): Extract multi-scale features. Defaults to True.
|
||||
layer_names (tuple, optional): Layers used for feature extraction. Order = (head output features, last layer features, ...decoder features). Defaults to ('out_conv', 'l4_rn', 'r4', 'r3', 'r2', 'r1').
|
||||
freeze_bn (bool, optional): Freeze BatchNorm. Generally results in better finetuning performance. Defaults to False.
|
||||
keep_aspect_ratio (bool, optional): Keep the aspect ratio of input images while resizing. Defaults to True.
|
||||
img_size (int, tuple, optional): Input resolution. Defaults to 384.
|
||||
"""
|
||||
super().__init__()
|
||||
self.core = midas
|
||||
self.output_channels = None
|
||||
self.core_out = {}
|
||||
self.trainable = trainable
|
||||
self.fetch_features = fetch_features
|
||||
# midas.scratch.output_conv = nn.Identity()
|
||||
self.handles = []
|
||||
# self.layer_names = ['out_conv','l4_rn', 'r4', 'r3', 'r2', 'r1']
|
||||
self.layer_names = layer_names
|
||||
|
||||
self.set_trainable(trainable)
|
||||
self.set_fetch_features(fetch_features)
|
||||
|
||||
self.prep = PrepForMidas(keep_aspect_ratio=keep_aspect_ratio,
|
||||
img_size=img_size, do_resize=kwargs.get('do_resize', True))
|
||||
|
||||
if freeze_bn:
|
||||
self.freeze_bn()
|
||||
|
||||
def set_trainable(self, trainable):
|
||||
self.trainable = trainable
|
||||
if trainable:
|
||||
self.unfreeze()
|
||||
else:
|
||||
self.freeze()
|
||||
return self
|
||||
|
||||
def set_fetch_features(self, fetch_features):
|
||||
self.fetch_features = fetch_features
|
||||
if fetch_features:
|
||||
if len(self.handles) == 0:
|
||||
self.attach_hooks(self.core)
|
||||
else:
|
||||
self.remove_hooks()
|
||||
return self
|
||||
|
||||
def freeze(self):
|
||||
for p in self.parameters():
|
||||
p.requires_grad = False
|
||||
self.trainable = False
|
||||
return self
|
||||
|
||||
def unfreeze(self):
|
||||
for p in self.parameters():
|
||||
p.requires_grad = True
|
||||
self.trainable = True
|
||||
return self
|
||||
|
||||
def freeze_bn(self):
|
||||
for m in self.modules():
|
||||
if isinstance(m, nn.BatchNorm2d):
|
||||
m.eval()
|
||||
return self
|
||||
|
||||
def forward(self, x, denorm=False, return_rel_depth=False):
|
||||
with torch.no_grad():
|
||||
if denorm:
|
||||
x = denormalize(x)
|
||||
x = self.prep(x)
|
||||
# print("Shape after prep: ", x.shape)
|
||||
|
||||
with torch.set_grad_enabled(self.trainable):
|
||||
|
||||
# print("Input size to Midascore", x.shape)
|
||||
rel_depth = self.core(x)
|
||||
# print("Output from midas shape", rel_depth.shape)
|
||||
if not self.fetch_features:
|
||||
return rel_depth
|
||||
out = [self.core_out[k] for k in self.layer_names]
|
||||
|
||||
if return_rel_depth:
|
||||
return rel_depth, out
|
||||
return out
|
||||
|
||||
def get_rel_pos_params(self):
|
||||
for name, p in self.core.pretrained.named_parameters():
|
||||
if "relative_position" in name:
|
||||
yield p
|
||||
|
||||
def get_enc_params_except_rel_pos(self):
|
||||
for name, p in self.core.pretrained.named_parameters():
|
||||
if "relative_position" not in name:
|
||||
yield p
|
||||
|
||||
def freeze_encoder(self, freeze_rel_pos=False):
|
||||
if freeze_rel_pos:
|
||||
for p in self.core.pretrained.parameters():
|
||||
p.requires_grad = False
|
||||
else:
|
||||
for p in self.get_enc_params_except_rel_pos():
|
||||
p.requires_grad = False
|
||||
return self
|
||||
|
||||
def attach_hooks(self, midas):
|
||||
if len(self.handles) > 0:
|
||||
self.remove_hooks()
|
||||
if "out_conv" in self.layer_names:
|
||||
self.handles.append(list(midas.scratch.output_conv.children())[
|
||||
3].register_forward_hook(get_activation("out_conv", self.core_out)))
|
||||
if "r4" in self.layer_names:
|
||||
self.handles.append(midas.scratch.refinenet4.register_forward_hook(
|
||||
get_activation("r4", self.core_out)))
|
||||
if "r3" in self.layer_names:
|
||||
self.handles.append(midas.scratch.refinenet3.register_forward_hook(
|
||||
get_activation("r3", self.core_out)))
|
||||
if "r2" in self.layer_names:
|
||||
self.handles.append(midas.scratch.refinenet2.register_forward_hook(
|
||||
get_activation("r2", self.core_out)))
|
||||
if "r1" in self.layer_names:
|
||||
self.handles.append(midas.scratch.refinenet1.register_forward_hook(
|
||||
get_activation("r1", self.core_out)))
|
||||
if "l4_rn" in self.layer_names:
|
||||
self.handles.append(midas.scratch.layer4_rn.register_forward_hook(
|
||||
get_activation("l4_rn", self.core_out)))
|
||||
|
||||
return self
|
||||
|
||||
def remove_hooks(self):
|
||||
for h in self.handles:
|
||||
h.remove()
|
||||
return self
|
||||
|
||||
def __del__(self):
|
||||
self.remove_hooks()
|
||||
|
||||
def set_output_channels(self, model_type):
|
||||
self.output_channels = MIDAS_SETTINGS[model_type]
|
||||
|
||||
@staticmethod
|
||||
def build(midas_model_type="DPT_BEiT_L_384", train_midas=False, use_pretrained_midas=True, fetch_features=False, freeze_bn=True, force_keep_ar=False, force_reload=False, **kwargs):
|
||||
if midas_model_type not in MIDAS_SETTINGS:
|
||||
raise ValueError(
|
||||
f"Invalid model type: {midas_model_type}. Must be one of {list(MIDAS_SETTINGS.keys())}")
|
||||
if "img_size" in kwargs:
|
||||
kwargs = MidasCore.parse_img_size(kwargs)
|
||||
img_size = kwargs.pop("img_size", [384, 384])
|
||||
print("img_size", img_size)
|
||||
midas_path = os.path.join(os.path.dirname(__file__), 'midas_repo')
|
||||
midas = torch.hub.load(midas_path, midas_model_type,
|
||||
pretrained=use_pretrained_midas, force_reload=force_reload, source='local')
|
||||
kwargs.update({'keep_aspect_ratio': force_keep_ar})
|
||||
midas_core = MidasCore(midas, trainable=train_midas, fetch_features=fetch_features,
|
||||
freeze_bn=freeze_bn, img_size=img_size, **kwargs)
|
||||
midas_core.set_output_channels(midas_model_type)
|
||||
return midas_core
|
||||
|
||||
@staticmethod
|
||||
def build_from_config(config):
|
||||
return MidasCore.build(**config)
|
||||
|
||||
@staticmethod
|
||||
def parse_img_size(config):
|
||||
assert 'img_size' in config
|
||||
if isinstance(config['img_size'], str):
|
||||
assert "," in config['img_size'], "img_size should be a string with comma separated img_size=H,W"
|
||||
config['img_size'] = list(map(int, config['img_size'].split(",")))
|
||||
assert len(
|
||||
config['img_size']) == 2, "img_size should be a string with comma separated img_size=H,W"
|
||||
elif isinstance(config['img_size'], int):
|
||||
config['img_size'] = [config['img_size'], config['img_size']]
|
||||
else:
|
||||
assert isinstance(config['img_size'], list) and len(
|
||||
config['img_size']) == 2, "img_size should be a list of H,W"
|
||||
return config
|
||||
|
||||
|
||||
nchannels2models = {
|
||||
tuple([256]*5): ["DPT_BEiT_L_384", "DPT_BEiT_L_512", "DPT_BEiT_B_384", "DPT_SwinV2_L_384", "DPT_SwinV2_B_384", "DPT_SwinV2_T_256", "DPT_Large", "DPT_Hybrid"],
|
||||
(512, 256, 128, 64, 64): ["MiDaS_small"]
|
||||
}
|
||||
|
||||
# Model name to number of output channels
|
||||
MIDAS_SETTINGS = {m: k for k, v in nchannels2models.items()
|
||||
for m in v
|
||||
}
|
||||
@@ -0,0 +1,110 @@
|
||||
# Byte-compiled / optimized / DLL files
|
||||
__pycache__/
|
||||
*.py[cod]
|
||||
*$py.class
|
||||
|
||||
# C extensions
|
||||
*.so
|
||||
|
||||
# Distribution / packaging
|
||||
.Python
|
||||
build/
|
||||
develop-eggs/
|
||||
dist/
|
||||
downloads/
|
||||
eggs/
|
||||
.eggs/
|
||||
lib/
|
||||
lib64/
|
||||
parts/
|
||||
sdist/
|
||||
var/
|
||||
wheels/
|
||||
*.egg-info/
|
||||
.installed.cfg
|
||||
*.egg
|
||||
MANIFEST
|
||||
|
||||
# PyInstaller
|
||||
# Usually these files are written by a python script from a template
|
||||
# before PyInstaller builds the exe, so as to inject date/other infos into it.
|
||||
*.manifest
|
||||
*.spec
|
||||
|
||||
# Installer logs
|
||||
pip-log.txt
|
||||
pip-delete-this-directory.txt
|
||||
|
||||
# Unit test / coverage reports
|
||||
htmlcov/
|
||||
.tox/
|
||||
.coverage
|
||||
.coverage.*
|
||||
.cache
|
||||
nosetests.xml
|
||||
coverage.xml
|
||||
*.cover
|
||||
.hypothesis/
|
||||
.pytest_cache/
|
||||
|
||||
# Translations
|
||||
*.mo
|
||||
*.pot
|
||||
|
||||
# Django stuff:
|
||||
*.log
|
||||
local_settings.py
|
||||
db.sqlite3
|
||||
|
||||
# Flask stuff:
|
||||
instance/
|
||||
.webassets-cache
|
||||
|
||||
# Scrapy stuff:
|
||||
.scrapy
|
||||
|
||||
# Sphinx documentation
|
||||
docs/_build/
|
||||
|
||||
# PyBuilder
|
||||
target/
|
||||
|
||||
# Jupyter Notebook
|
||||
.ipynb_checkpoints
|
||||
|
||||
# pyenv
|
||||
.python-version
|
||||
|
||||
# celery beat schedule file
|
||||
celerybeat-schedule
|
||||
|
||||
# SageMath parsed files
|
||||
*.sage.py
|
||||
|
||||
# Environments
|
||||
.env
|
||||
.venv
|
||||
env/
|
||||
venv/
|
||||
ENV/
|
||||
env.bak/
|
||||
venv.bak/
|
||||
|
||||
# Spyder project settings
|
||||
.spyderproject
|
||||
.spyproject
|
||||
|
||||
# Rope project settings
|
||||
.ropeproject
|
||||
|
||||
# mkdocs documentation
|
||||
/site
|
||||
|
||||
# mypy
|
||||
.mypy_cache/
|
||||
|
||||
*.png
|
||||
*.pfm
|
||||
*.jpg
|
||||
*.jpeg
|
||||
*.pt
|
||||
@@ -0,0 +1,29 @@
|
||||
# enables cuda support in docker
|
||||
FROM nvidia/cuda:10.2-cudnn7-runtime-ubuntu18.04
|
||||
|
||||
# install python 3.6, pip and requirements for opencv-python
|
||||
# (see https://github.com/NVIDIA/nvidia-docker/issues/864)
|
||||
RUN apt-get update && apt-get -y install \
|
||||
python3 \
|
||||
python3-pip \
|
||||
libsm6 \
|
||||
libxext6 \
|
||||
libxrender-dev \
|
||||
curl \
|
||||
&& rm -rf /var/lib/apt/lists/*
|
||||
|
||||
# install python dependencies
|
||||
RUN pip3 install --upgrade pip
|
||||
RUN pip3 install torch~=1.8 torchvision opencv-python-headless~=3.4 timm
|
||||
|
||||
# copy inference code
|
||||
WORKDIR /opt/MiDaS
|
||||
COPY ./midas ./midas
|
||||
COPY ./*.py ./
|
||||
|
||||
# download model weights so the docker image can be used offline
|
||||
RUN cd weights && {curl -OL https://github.com/isl-org/MiDaS/releases/download/v3/dpt_hybrid_384.pt; cd -; }
|
||||
RUN python3 run.py --model_type dpt_hybrid; exit 0
|
||||
|
||||
# entrypoint (dont forget to mount input and output directories)
|
||||
CMD python3 run.py --model_type dpt_hybrid
|
||||
@@ -0,0 +1,21 @@
|
||||
MIT License
|
||||
|
||||
Copyright (c) 2019 Intel ISL (Intel Intelligent Systems Lab)
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
of this software and associated documentation files (the "Software"), to deal
|
||||
in the Software without restriction, including without limitation the rights
|
||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
copies of the Software, and to permit persons to whom the Software is
|
||||
furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all
|
||||
copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
SOFTWARE.
|
||||
@@ -0,0 +1,259 @@
|
||||
## Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-shot Cross-dataset Transfer
|
||||
|
||||
This repository contains code to compute depth from a single image. It accompanies our [paper](https://arxiv.org/abs/1907.01341v3):
|
||||
|
||||
>Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-shot Cross-dataset Transfer
|
||||
René Ranftl, Katrin Lasinger, David Hafner, Konrad Schindler, Vladlen Koltun
|
||||
|
||||
|
||||
and our [preprint](https://arxiv.org/abs/2103.13413):
|
||||
|
||||
> Vision Transformers for Dense Prediction
|
||||
> René Ranftl, Alexey Bochkovskiy, Vladlen Koltun
|
||||
|
||||
|
||||
MiDaS was trained on up to 12 datasets (ReDWeb, DIML, Movies, MegaDepth, WSVD, TartanAir, HRWSI, ApolloScape, BlendedMVS, IRS, KITTI, NYU Depth V2) with
|
||||
multi-objective optimization.
|
||||
The original model that was trained on 5 datasets (`MIX 5` in the paper) can be found [here](https://github.com/isl-org/MiDaS/releases/tag/v2).
|
||||
The figure below shows an overview of the different MiDaS models; the bubble size scales with number of parameters.
|
||||
|
||||

|
||||
|
||||
### Setup
|
||||
|
||||
1) Pick one or more models and download the corresponding weights to the `weights` folder:
|
||||
|
||||
MiDaS 3.1
|
||||
- For highest quality: [dpt_beit_large_512](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_large_512.pt)
|
||||
- For moderately less quality, but better speed-performance trade-off: [dpt_swin2_large_384](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_large_384.pt)
|
||||
- For embedded devices: [dpt_swin2_tiny_256](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_tiny_256.pt), [dpt_levit_224](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_levit_224.pt)
|
||||
- For inference on Intel CPUs, OpenVINO may be used for the small legacy model: openvino_midas_v21_small [.xml](https://github.com/isl-org/MiDaS/releases/download/v3_1/openvino_midas_v21_small_256.xml), [.bin](https://github.com/isl-org/MiDaS/releases/download/v3_1/openvino_midas_v21_small_256.bin)
|
||||
|
||||
MiDaS 3.0: Legacy transformer models [dpt_large_384](https://github.com/isl-org/MiDaS/releases/download/v3/dpt_large_384.pt) and [dpt_hybrid_384](https://github.com/isl-org/MiDaS/releases/download/v3/dpt_hybrid_384.pt)
|
||||
|
||||
MiDaS 2.1: Legacy convolutional models [midas_v21_384](https://github.com/isl-org/MiDaS/releases/download/v2_1/midas_v21_384.pt) and [midas_v21_small_256](https://github.com/isl-org/MiDaS/releases/download/v2_1/midas_v21_small_256.pt)
|
||||
|
||||
1) Set up dependencies:
|
||||
|
||||
```shell
|
||||
conda env create -f environment.yaml
|
||||
conda activate midas-py310
|
||||
```
|
||||
|
||||
#### optional
|
||||
|
||||
For the Next-ViT model, execute
|
||||
|
||||
```shell
|
||||
git submodule add https://github.com/isl-org/Next-ViT midas/external/next_vit
|
||||
```
|
||||
|
||||
For the OpenVINO model, install
|
||||
|
||||
```shell
|
||||
pip install openvino
|
||||
```
|
||||
|
||||
### Usage
|
||||
|
||||
1) Place one or more input images in the folder `input`.
|
||||
|
||||
2) Run the model with
|
||||
|
||||
```shell
|
||||
python run.py --model_type <model_type> --input_path input --output_path output
|
||||
```
|
||||
where ```<model_type>``` is chosen from [dpt_beit_large_512](#model_type), [dpt_beit_large_384](#model_type),
|
||||
[dpt_beit_base_384](#model_type), [dpt_swin2_large_384](#model_type), [dpt_swin2_base_384](#model_type),
|
||||
[dpt_swin2_tiny_256](#model_type), [dpt_swin_large_384](#model_type), [dpt_next_vit_large_384](#model_type),
|
||||
[dpt_levit_224](#model_type), [dpt_large_384](#model_type), [dpt_hybrid_384](#model_type),
|
||||
[midas_v21_384](#model_type), [midas_v21_small_256](#model_type), [openvino_midas_v21_small_256](#model_type).
|
||||
|
||||
3) The resulting depth maps are written to the `output` folder.
|
||||
|
||||
#### optional
|
||||
|
||||
1) By default, the inference resizes the height of input images to the size of a model to fit into the encoder. This
|
||||
size is given by the numbers in the model names of the [accuracy table](#accuracy). Some models do not only support a single
|
||||
inference height but a range of different heights. Feel free to explore different heights by appending the extra
|
||||
command line argument `--height`. Unsupported height values will throw an error. Note that using this argument may
|
||||
decrease the model accuracy.
|
||||
2) By default, the inference keeps the aspect ratio of input images when feeding them into the encoder if this is
|
||||
supported by a model (all models except for Swin, Swin2, LeViT). In order to resize to a square resolution,
|
||||
disregarding the aspect ratio while preserving the height, use the command line argument `--square`.
|
||||
|
||||
#### via Camera
|
||||
|
||||
If you want the input images to be grabbed from the camera and shown in a window, leave the input and output paths
|
||||
away and choose a model type as shown above:
|
||||
|
||||
```shell
|
||||
python run.py --model_type <model_type> --side
|
||||
```
|
||||
|
||||
The argument `--side` is optional and causes both the input RGB image and the output depth map to be shown
|
||||
side-by-side for comparison.
|
||||
|
||||
#### via Docker
|
||||
|
||||
1) Make sure you have installed Docker and the
|
||||
[NVIDIA Docker runtime](https://github.com/NVIDIA/nvidia-docker/wiki/Installation-\(Native-GPU-Support\)).
|
||||
|
||||
2) Build the Docker image:
|
||||
|
||||
```shell
|
||||
docker build -t midas .
|
||||
```
|
||||
|
||||
3) Run inference:
|
||||
|
||||
```shell
|
||||
docker run --rm --gpus all -v $PWD/input:/opt/MiDaS/input -v $PWD/output:/opt/MiDaS/output -v $PWD/weights:/opt/MiDaS/weights midas
|
||||
```
|
||||
|
||||
This command passes through all of your NVIDIA GPUs to the container, mounts the
|
||||
`input` and `output` directories and then runs the inference.
|
||||
|
||||
#### via PyTorch Hub
|
||||
|
||||
The pretrained model is also available on [PyTorch Hub](https://pytorch.org/hub/intelisl_midas_v2/)
|
||||
|
||||
#### via TensorFlow or ONNX
|
||||
|
||||
See [README](https://github.com/isl-org/MiDaS/tree/master/tf) in the `tf` subdirectory.
|
||||
|
||||
Currently only supports MiDaS v2.1.
|
||||
|
||||
|
||||
#### via Mobile (iOS / Android)
|
||||
|
||||
See [README](https://github.com/isl-org/MiDaS/tree/master/mobile) in the `mobile` subdirectory.
|
||||
|
||||
#### via ROS1 (Robot Operating System)
|
||||
|
||||
See [README](https://github.com/isl-org/MiDaS/tree/master/ros) in the `ros` subdirectory.
|
||||
|
||||
Currently only supports MiDaS v2.1. DPT-based models to be added.
|
||||
|
||||
|
||||
### Accuracy
|
||||
|
||||
We provide a **zero-shot error** $\epsilon_d$ which is evaluated for 6 different datasets
|
||||
(see [paper](https://arxiv.org/abs/1907.01341v3)). **Lower error values are better**.
|
||||
$\color{green}{\textsf{Overall model quality is represented by the improvement}}$ ([Imp.](#improvement)) with respect to
|
||||
MiDaS 3.0 DPT<sub>L-384</sub>. The models are grouped by the height used for inference, whereas the square training resolution is given by
|
||||
the numbers in the model names. The table also shows the **number of parameters** (in millions) and the
|
||||
**frames per second** for inference at the training resolution (for GPU RTX 3090):
|
||||
|
||||
| MiDaS Model | DIW </br><sup>WHDR</sup> | Eth3d </br><sup>AbsRel</sup> | Sintel </br><sup>AbsRel</sup> | TUM </br><sup>δ1</sup> | KITTI </br><sup>δ1</sup> | NYUv2 </br><sup>δ1</sup> | $\color{green}{\textsf{Imp.}}$ </br><sup>%</sup> | Par.</br><sup>M</sup> | FPS</br><sup> </sup> |
|
||||
|-----------------------------------------------------------------------------------------------------------------------|-------------------------:|-----------------------------:|------------------------------:|-------------------------:|-------------------------:|-------------------------:|-------------------------------------------------:|----------------------:|--------------------------:|
|
||||
| **Inference height 512** | | | | | | | | | |
|
||||
| [v3.1 BEiT<sub>L-512</sub>](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_large_512.pt) | 0.1137 | 0.0659 | 0.2366 | **6.13** | 11.56* | **1.86*** | $\color{green}{\textsf{19}}$ | **345** | **5.7** |
|
||||
| [v3.1 BEiT<sub>L-512</sub>](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_large_512.pt)$\tiny{\square}$ | **0.1121** | **0.0614** | **0.2090** | 6.46 | **5.00*** | 1.90* | $\color{green}{\textsf{34}}$ | **345** | **5.7** |
|
||||
| | | | | | | | | | |
|
||||
| **Inference height 384** | | | | | | | | | |
|
||||
| [v3.1 BEiT<sub>L-512</sub>](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_large_512.pt) | 0.1245 | 0.0681 | **0.2176** | **6.13** | 6.28* | **2.16*** | $\color{green}{\textsf{28}}$ | 345 | 12 |
|
||||
| [v3.1 Swin2<sub>L-384</sub>](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_large_384.pt)$\tiny{\square}$ | 0.1106 | 0.0732 | 0.2442 | 8.87 | **5.84*** | 2.92* | $\color{green}{\textsf{22}}$ | 213 | 41 |
|
||||
| [v3.1 Swin2<sub>B-384</sub>](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_base_384.pt)$\tiny{\square}$ | 0.1095 | 0.0790 | 0.2404 | 8.93 | 5.97* | 3.28* | $\color{green}{\textsf{22}}$ | 102 | 39 |
|
||||
| [v3.1 Swin<sub>L-384</sub>](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin_large_384.pt)$\tiny{\square}$ | 0.1126 | 0.0853 | 0.2428 | 8.74 | 6.60* | 3.34* | $\color{green}{\textsf{17}}$ | 213 | 49 |
|
||||
| [v3.1 BEiT<sub>L-384</sub>](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_large_384.pt) | 0.1239 | **0.0667** | 0.2545 | 7.17 | 9.84* | 2.21* | $\color{green}{\textsf{17}}$ | 344 | 13 |
|
||||
| [v3.1 Next-ViT<sub>L-384</sub>](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_next_vit_large_384.pt) | **0.1031** | 0.0954 | 0.2295 | 9.21 | 6.89* | 3.47* | $\color{green}{\textsf{16}}$ | **72** | 30 |
|
||||
| [v3.1 BEiT<sub>B-384</sub>](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_base_384.pt) | 0.1159 | 0.0967 | 0.2901 | 9.88 | 26.60* | 3.91* | $\color{green}{\textsf{-31}}$ | 112 | 31 |
|
||||
| [v3.0 DPT<sub>L-384</sub>](https://github.com/isl-org/MiDaS/releases/download/v3/dpt_large_384.pt) | 0.1082 | 0.0888 | 0.2697 | 9.97 | 8.46 | 8.32 | $\color{green}{\textsf{0}}$ | 344 | **61** |
|
||||
| [v3.0 DPT<sub>H-384</sub>](https://github.com/isl-org/MiDaS/releases/download/v3/dpt_hybrid_384.pt) | 0.1106 | 0.0934 | 0.2741 | 10.89 | 11.56 | 8.69 | $\color{green}{\textsf{-10}}$ | 123 | 50 |
|
||||
| [v2.1 Large<sub>384</sub>](https://github.com/isl-org/MiDaS/releases/download/v2_1/midas_v21_384.pt) | 0.1295 | 0.1155 | 0.3285 | 12.51 | 16.08 | 8.71 | $\color{green}{\textsf{-32}}$ | 105 | 47 |
|
||||
| | | | | | | | | | |
|
||||
| **Inference height 256** | | | | | | | | | |
|
||||
| [v3.1 Swin2<sub>T-256</sub>](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_tiny_256.pt)$\tiny{\square}$ | **0.1211** | **0.1106** | **0.2868** | **13.43** | **10.13*** | **5.55*** | $\color{green}{\textsf{-11}}$ | 42 | 64 |
|
||||
| [v2.1 Small<sub>256</sub>](https://github.com/isl-org/MiDaS/releases/download/v2_1/midas_v21_small_256.pt) | 0.1344 | 0.1344 | 0.3370 | 14.53 | 29.27 | 13.43 | $\color{green}{\textsf{-76}}$ | **21** | **90** |
|
||||
| | | | | | | | | | |
|
||||
| **Inference height 224** | | | | | | | | | |
|
||||
| [v3.1 LeViT<sub>224</sub>](https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_levit_224.pt)$\tiny{\square}$ | **0.1314** | **0.1206** | **0.3148** | **18.21** | **15.27*** | **8.64*** | $\color{green}{\textsf{-40}}$ | **51** | **73** |
|
||||
|
||||
* No zero-shot error, because models are also trained on KITTI and NYU Depth V2\
|
||||
$\square$ Validation performed at **square resolution**, either because the transformer encoder backbone of a model
|
||||
does not support non-square resolutions (Swin, Swin2, LeViT) or for comparison with these models. All other
|
||||
validations keep the aspect ratio. A difference in resolution limits the comparability of the zero-shot error and the
|
||||
improvement, because these quantities are averages over the pixels of an image and do not take into account the
|
||||
advantage of more details due to a higher resolution.\
|
||||
Best values per column and same validation height in bold
|
||||
|
||||
#### Improvement
|
||||
|
||||
The improvement in the above table is defined as the relative zero-shot error with respect to MiDaS v3.0
|
||||
DPT<sub>L-384</sub> and averaging over the datasets. So, if $\epsilon_d$ is the zero-shot error for dataset $d$, then
|
||||
the $\color{green}{\textsf{improvement}}$ is given by $100(1-(1/6)\sum_d\epsilon_d/\epsilon_{d,\rm{DPT_{L-384}}})$%.
|
||||
|
||||
Note that the improvements of 10% for MiDaS v2.0 → v2.1 and 21% for MiDaS v2.1 → v3.0 are not visible from the
|
||||
improvement column (Imp.) in the table but would require an evaluation with respect to MiDaS v2.1 Large<sub>384</sub>
|
||||
and v2.0 Large<sub>384</sub> respectively instead of v3.0 DPT<sub>L-384</sub>.
|
||||
|
||||
### Depth map comparison
|
||||
|
||||
Zoom in for better visibility
|
||||

|
||||
|
||||
### Speed on Camera Feed
|
||||
|
||||
Test configuration
|
||||
- Windows 10
|
||||
- 11th Gen Intel Core i7-1185G7 3.00GHz
|
||||
- 16GB RAM
|
||||
- Camera resolution 640x480
|
||||
- openvino_midas_v21_small_256
|
||||
|
||||
Speed: 22 FPS
|
||||
|
||||
### Changelog
|
||||
|
||||
* [Dec 2022] Released MiDaS v3.1:
|
||||
- New models based on 5 different types of transformers ([BEiT](https://arxiv.org/pdf/2106.08254.pdf), [Swin2](https://arxiv.org/pdf/2111.09883.pdf), [Swin](https://arxiv.org/pdf/2103.14030.pdf), [Next-ViT](https://arxiv.org/pdf/2207.05501.pdf), [LeViT](https://arxiv.org/pdf/2104.01136.pdf))
|
||||
- Training datasets extended from 10 to 12, including also KITTI and NYU Depth V2 using [BTS](https://github.com/cleinc/bts) split
|
||||
- Best model, BEiT<sub>Large 512</sub>, with resolution 512x512, is on average about [28% more accurate](#Accuracy) than MiDaS v3.0
|
||||
- Integrated live depth estimation from camera feed
|
||||
* [Sep 2021] Integrated to [Huggingface Spaces](https://huggingface.co/spaces) with [Gradio](https://github.com/gradio-app/gradio). See [Gradio Web Demo](https://huggingface.co/spaces/akhaliq/DPT-Large).
|
||||
* [Apr 2021] Released MiDaS v3.0:
|
||||
- New models based on [Dense Prediction Transformers](https://arxiv.org/abs/2103.13413) are on average [21% more accurate](#Accuracy) than MiDaS v2.1
|
||||
- Additional models can be found [here](https://github.com/isl-org/DPT)
|
||||
* [Nov 2020] Released MiDaS v2.1:
|
||||
- New model that was trained on 10 datasets and is on average about [10% more accurate](#Accuracy) than [MiDaS v2.0](https://github.com/isl-org/MiDaS/releases/tag/v2)
|
||||
- New light-weight model that achieves [real-time performance](https://github.com/isl-org/MiDaS/tree/master/mobile) on mobile platforms.
|
||||
- Sample applications for [iOS](https://github.com/isl-org/MiDaS/tree/master/mobile/ios) and [Android](https://github.com/isl-org/MiDaS/tree/master/mobile/android)
|
||||
- [ROS package](https://github.com/isl-org/MiDaS/tree/master/ros) for easy deployment on robots
|
||||
* [Jul 2020] Added TensorFlow and ONNX code. Added [online demo](http://35.202.76.57/).
|
||||
* [Dec 2019] Released new version of MiDaS - the new model is significantly more accurate and robust
|
||||
* [Jul 2019] Initial release of MiDaS ([Link](https://github.com/isl-org/MiDaS/releases/tag/v1))
|
||||
|
||||
### Citation
|
||||
|
||||
Please cite our paper if you use this code or any of the models:
|
||||
```
|
||||
@ARTICLE {Ranftl2022,
|
||||
author = "Ren\'{e} Ranftl and Katrin Lasinger and David Hafner and Konrad Schindler and Vladlen Koltun",
|
||||
title = "Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-Shot Cross-Dataset Transfer",
|
||||
journal = "IEEE Transactions on Pattern Analysis and Machine Intelligence",
|
||||
year = "2022",
|
||||
volume = "44",
|
||||
number = "3"
|
||||
}
|
||||
```
|
||||
|
||||
If you use a DPT-based model, please also cite:
|
||||
|
||||
```
|
||||
@article{Ranftl2021,
|
||||
author = {Ren\'{e} Ranftl and Alexey Bochkovskiy and Vladlen Koltun},
|
||||
title = {Vision Transformers for Dense Prediction},
|
||||
journal = {ICCV},
|
||||
year = {2021},
|
||||
}
|
||||
```
|
||||
|
||||
### Acknowledgements
|
||||
|
||||
Our work builds on and uses code from [timm](https://github.com/rwightman/pytorch-image-models) and [Next-ViT](https://github.com/bytedance/Next-ViT).
|
||||
We'd like to thank the authors for making these libraries available.
|
||||
|
||||
### License
|
||||
|
||||
MIT License
|
||||
@@ -0,0 +1,16 @@
|
||||
name: midas-py310
|
||||
channels:
|
||||
- pytorch
|
||||
- defaults
|
||||
dependencies:
|
||||
- nvidia::cudatoolkit=11.7
|
||||
- python=3.10.8
|
||||
- pytorch::pytorch=1.13.0
|
||||
- torchvision=0.14.0
|
||||
- pip=22.3.1
|
||||
- numpy=1.23.4
|
||||
- pip:
|
||||
- opencv-python==4.6.0.66
|
||||
- imutils==0.5.4
|
||||
- timm==0.6.12
|
||||
- einops==0.6.0
|
||||
@@ -0,0 +1,435 @@
|
||||
dependencies = ["torch"]
|
||||
|
||||
import torch
|
||||
from midas.dpt_depth import DPTDepthModel
|
||||
from midas.midas_net import MidasNet
|
||||
from midas.midas_net_custom import MidasNet_small
|
||||
|
||||
|
||||
def DPT_BEiT_L_512(pretrained=True, **kwargs):
|
||||
""" # This docstring shows up in hub.help()
|
||||
MiDaS DPT_BEiT_L_512 model for monocular depth estimation
|
||||
pretrained (bool): load pretrained weights into model
|
||||
"""
|
||||
|
||||
model = DPTDepthModel(
|
||||
path=None,
|
||||
backbone="beitl16_512",
|
||||
non_negative=True,
|
||||
)
|
||||
|
||||
if pretrained:
|
||||
checkpoint = (
|
||||
"https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_large_512.pt"
|
||||
)
|
||||
state_dict = torch.hub.load_state_dict_from_url(
|
||||
checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
|
||||
)
|
||||
model.load_state_dict(state_dict)
|
||||
|
||||
return model
|
||||
|
||||
def DPT_BEiT_L_384(pretrained=True, **kwargs):
|
||||
""" # This docstring shows up in hub.help()
|
||||
MiDaS DPT_BEiT_L_384 model for monocular depth estimation
|
||||
pretrained (bool): load pretrained weights into model
|
||||
"""
|
||||
|
||||
model = DPTDepthModel(
|
||||
path=None,
|
||||
backbone="beitl16_384",
|
||||
non_negative=True,
|
||||
)
|
||||
|
||||
if pretrained:
|
||||
checkpoint = (
|
||||
"https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_large_384.pt"
|
||||
)
|
||||
state_dict = torch.hub.load_state_dict_from_url(
|
||||
checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
|
||||
)
|
||||
model.load_state_dict(state_dict)
|
||||
|
||||
return model
|
||||
|
||||
def DPT_BEiT_B_384(pretrained=True, **kwargs):
|
||||
""" # This docstring shows up in hub.help()
|
||||
MiDaS DPT_BEiT_B_384 model for monocular depth estimation
|
||||
pretrained (bool): load pretrained weights into model
|
||||
"""
|
||||
|
||||
model = DPTDepthModel(
|
||||
path=None,
|
||||
backbone="beitb16_384",
|
||||
non_negative=True,
|
||||
)
|
||||
|
||||
if pretrained:
|
||||
checkpoint = (
|
||||
"https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_beit_base_384.pt"
|
||||
)
|
||||
state_dict = torch.hub.load_state_dict_from_url(
|
||||
checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
|
||||
)
|
||||
model.load_state_dict(state_dict)
|
||||
|
||||
return model
|
||||
|
||||
def DPT_SwinV2_L_384(pretrained=True, **kwargs):
|
||||
""" # This docstring shows up in hub.help()
|
||||
MiDaS DPT_SwinV2_L_384 model for monocular depth estimation
|
||||
pretrained (bool): load pretrained weights into model
|
||||
"""
|
||||
|
||||
model = DPTDepthModel(
|
||||
path=None,
|
||||
backbone="swin2l24_384",
|
||||
non_negative=True,
|
||||
)
|
||||
|
||||
if pretrained:
|
||||
checkpoint = (
|
||||
"https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_large_384.pt"
|
||||
)
|
||||
state_dict = torch.hub.load_state_dict_from_url(
|
||||
checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
|
||||
)
|
||||
model.load_state_dict(state_dict)
|
||||
|
||||
return model
|
||||
|
||||
def DPT_SwinV2_B_384(pretrained=True, **kwargs):
|
||||
""" # This docstring shows up in hub.help()
|
||||
MiDaS DPT_SwinV2_B_384 model for monocular depth estimation
|
||||
pretrained (bool): load pretrained weights into model
|
||||
"""
|
||||
|
||||
model = DPTDepthModel(
|
||||
path=None,
|
||||
backbone="swin2b24_384",
|
||||
non_negative=True,
|
||||
)
|
||||
|
||||
if pretrained:
|
||||
checkpoint = (
|
||||
"https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_base_384.pt"
|
||||
)
|
||||
state_dict = torch.hub.load_state_dict_from_url(
|
||||
checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
|
||||
)
|
||||
model.load_state_dict(state_dict)
|
||||
|
||||
return model
|
||||
|
||||
def DPT_SwinV2_T_256(pretrained=True, **kwargs):
|
||||
""" # This docstring shows up in hub.help()
|
||||
MiDaS DPT_SwinV2_T_256 model for monocular depth estimation
|
||||
pretrained (bool): load pretrained weights into model
|
||||
"""
|
||||
|
||||
model = DPTDepthModel(
|
||||
path=None,
|
||||
backbone="swin2t16_256",
|
||||
non_negative=True,
|
||||
)
|
||||
|
||||
if pretrained:
|
||||
checkpoint = (
|
||||
"https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin2_tiny_256.pt"
|
||||
)
|
||||
state_dict = torch.hub.load_state_dict_from_url(
|
||||
checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
|
||||
)
|
||||
model.load_state_dict(state_dict)
|
||||
|
||||
return model
|
||||
|
||||
def DPT_Swin_L_384(pretrained=True, **kwargs):
|
||||
""" # This docstring shows up in hub.help()
|
||||
MiDaS DPT_Swin_L_384 model for monocular depth estimation
|
||||
pretrained (bool): load pretrained weights into model
|
||||
"""
|
||||
|
||||
model = DPTDepthModel(
|
||||
path=None,
|
||||
backbone="swinl12_384",
|
||||
non_negative=True,
|
||||
)
|
||||
|
||||
if pretrained:
|
||||
checkpoint = (
|
||||
"https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_swin_large_384.pt"
|
||||
)
|
||||
state_dict = torch.hub.load_state_dict_from_url(
|
||||
checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
|
||||
)
|
||||
model.load_state_dict(state_dict)
|
||||
|
||||
return model
|
||||
|
||||
def DPT_Next_ViT_L_384(pretrained=True, **kwargs):
|
||||
""" # This docstring shows up in hub.help()
|
||||
MiDaS DPT_Next_ViT_L_384 model for monocular depth estimation
|
||||
pretrained (bool): load pretrained weights into model
|
||||
"""
|
||||
|
||||
model = DPTDepthModel(
|
||||
path=None,
|
||||
backbone="next_vit_large_6m",
|
||||
non_negative=True,
|
||||
)
|
||||
|
||||
if pretrained:
|
||||
checkpoint = (
|
||||
"https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_next_vit_large_384.pt"
|
||||
)
|
||||
state_dict = torch.hub.load_state_dict_from_url(
|
||||
checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
|
||||
)
|
||||
model.load_state_dict(state_dict)
|
||||
|
||||
return model
|
||||
|
||||
def DPT_LeViT_224(pretrained=True, **kwargs):
|
||||
""" # This docstring shows up in hub.help()
|
||||
MiDaS DPT_LeViT_224 model for monocular depth estimation
|
||||
pretrained (bool): load pretrained weights into model
|
||||
"""
|
||||
|
||||
model = DPTDepthModel(
|
||||
path=None,
|
||||
backbone="levit_384",
|
||||
non_negative=True,
|
||||
head_features_1=64,
|
||||
head_features_2=8,
|
||||
)
|
||||
|
||||
if pretrained:
|
||||
checkpoint = (
|
||||
"https://github.com/isl-org/MiDaS/releases/download/v3_1/dpt_levit_224.pt"
|
||||
)
|
||||
state_dict = torch.hub.load_state_dict_from_url(
|
||||
checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
|
||||
)
|
||||
model.load_state_dict(state_dict)
|
||||
|
||||
return model
|
||||
|
||||
def DPT_Large(pretrained=True, **kwargs):
|
||||
""" # This docstring shows up in hub.help()
|
||||
MiDaS DPT-Large model for monocular depth estimation
|
||||
pretrained (bool): load pretrained weights into model
|
||||
"""
|
||||
|
||||
model = DPTDepthModel(
|
||||
path=None,
|
||||
backbone="vitl16_384",
|
||||
non_negative=True,
|
||||
)
|
||||
|
||||
if pretrained:
|
||||
checkpoint = (
|
||||
"https://github.com/isl-org/MiDaS/releases/download/v3/dpt_large_384.pt"
|
||||
)
|
||||
state_dict = torch.hub.load_state_dict_from_url(
|
||||
checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
|
||||
)
|
||||
model.load_state_dict(state_dict)
|
||||
|
||||
return model
|
||||
|
||||
def DPT_Hybrid(pretrained=True, **kwargs):
|
||||
""" # This docstring shows up in hub.help()
|
||||
MiDaS DPT-Hybrid model for monocular depth estimation
|
||||
pretrained (bool): load pretrained weights into model
|
||||
"""
|
||||
|
||||
model = DPTDepthModel(
|
||||
path=None,
|
||||
backbone="vitb_rn50_384",
|
||||
non_negative=True,
|
||||
)
|
||||
|
||||
if pretrained:
|
||||
checkpoint = (
|
||||
"https://github.com/isl-org/MiDaS/releases/download/v3/dpt_hybrid_384.pt"
|
||||
)
|
||||
state_dict = torch.hub.load_state_dict_from_url(
|
||||
checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
|
||||
)
|
||||
model.load_state_dict(state_dict)
|
||||
|
||||
return model
|
||||
|
||||
def MiDaS(pretrained=True, **kwargs):
|
||||
""" # This docstring shows up in hub.help()
|
||||
MiDaS v2.1 model for monocular depth estimation
|
||||
pretrained (bool): load pretrained weights into model
|
||||
"""
|
||||
|
||||
model = MidasNet()
|
||||
|
||||
if pretrained:
|
||||
checkpoint = (
|
||||
"https://github.com/isl-org/MiDaS/releases/download/v2_1/midas_v21_384.pt"
|
||||
)
|
||||
state_dict = torch.hub.load_state_dict_from_url(
|
||||
checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
|
||||
)
|
||||
model.load_state_dict(state_dict)
|
||||
|
||||
return model
|
||||
|
||||
def MiDaS_small(pretrained=True, **kwargs):
|
||||
""" # This docstring shows up in hub.help()
|
||||
MiDaS v2.1 small model for monocular depth estimation on resource-constrained devices
|
||||
pretrained (bool): load pretrained weights into model
|
||||
"""
|
||||
|
||||
model = MidasNet_small(None, features=64, backbone="efficientnet_lite3", exportable=True, non_negative=True, blocks={'expand': True})
|
||||
|
||||
if pretrained:
|
||||
checkpoint = (
|
||||
"https://github.com/isl-org/MiDaS/releases/download/v2_1/midas_v21_small_256.pt"
|
||||
)
|
||||
state_dict = torch.hub.load_state_dict_from_url(
|
||||
checkpoint, map_location=torch.device('cpu'), progress=True, check_hash=True
|
||||
)
|
||||
model.load_state_dict(state_dict)
|
||||
|
||||
return model
|
||||
|
||||
|
||||
def transforms():
|
||||
import cv2
|
||||
from midas import transforms
|
||||
from midas.transforms import NormalizeImage, PrepareForNet, Resize
|
||||
from torchvision.transforms import Compose
|
||||
|
||||
transforms.default_transform = Compose(
|
||||
[
|
||||
lambda img: {"image": img / 255.0},
|
||||
Resize(
|
||||
384,
|
||||
384,
|
||||
resize_target=None,
|
||||
keep_aspect_ratio=True,
|
||||
ensure_multiple_of=32,
|
||||
resize_method="upper_bound",
|
||||
image_interpolation_method=cv2.INTER_CUBIC,
|
||||
),
|
||||
NormalizeImage(mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225]),
|
||||
PrepareForNet(),
|
||||
lambda sample: torch.from_numpy(sample["image"]).unsqueeze(0),
|
||||
]
|
||||
)
|
||||
|
||||
transforms.small_transform = Compose(
|
||||
[
|
||||
lambda img: {"image": img / 255.0},
|
||||
Resize(
|
||||
256,
|
||||
256,
|
||||
resize_target=None,
|
||||
keep_aspect_ratio=True,
|
||||
ensure_multiple_of=32,
|
||||
resize_method="upper_bound",
|
||||
image_interpolation_method=cv2.INTER_CUBIC,
|
||||
),
|
||||
NormalizeImage(mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225]),
|
||||
PrepareForNet(),
|
||||
lambda sample: torch.from_numpy(sample["image"]).unsqueeze(0),
|
||||
]
|
||||
)
|
||||
|
||||
transforms.dpt_transform = Compose(
|
||||
[
|
||||
lambda img: {"image": img / 255.0},
|
||||
Resize(
|
||||
384,
|
||||
384,
|
||||
resize_target=None,
|
||||
keep_aspect_ratio=True,
|
||||
ensure_multiple_of=32,
|
||||
resize_method="minimal",
|
||||
image_interpolation_method=cv2.INTER_CUBIC,
|
||||
),
|
||||
NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5]),
|
||||
PrepareForNet(),
|
||||
lambda sample: torch.from_numpy(sample["image"]).unsqueeze(0),
|
||||
]
|
||||
)
|
||||
|
||||
transforms.beit512_transform = Compose(
|
||||
[
|
||||
lambda img: {"image": img / 255.0},
|
||||
Resize(
|
||||
512,
|
||||
512,
|
||||
resize_target=None,
|
||||
keep_aspect_ratio=True,
|
||||
ensure_multiple_of=32,
|
||||
resize_method="minimal",
|
||||
image_interpolation_method=cv2.INTER_CUBIC,
|
||||
),
|
||||
NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5]),
|
||||
PrepareForNet(),
|
||||
lambda sample: torch.from_numpy(sample["image"]).unsqueeze(0),
|
||||
]
|
||||
)
|
||||
|
||||
transforms.swin384_transform = Compose(
|
||||
[
|
||||
lambda img: {"image": img / 255.0},
|
||||
Resize(
|
||||
384,
|
||||
384,
|
||||
resize_target=None,
|
||||
keep_aspect_ratio=False,
|
||||
ensure_multiple_of=32,
|
||||
resize_method="minimal",
|
||||
image_interpolation_method=cv2.INTER_CUBIC,
|
||||
),
|
||||
NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5]),
|
||||
PrepareForNet(),
|
||||
lambda sample: torch.from_numpy(sample["image"]).unsqueeze(0),
|
||||
]
|
||||
)
|
||||
|
||||
transforms.swin256_transform = Compose(
|
||||
[
|
||||
lambda img: {"image": img / 255.0},
|
||||
Resize(
|
||||
256,
|
||||
256,
|
||||
resize_target=None,
|
||||
keep_aspect_ratio=False,
|
||||
ensure_multiple_of=32,
|
||||
resize_method="minimal",
|
||||
image_interpolation_method=cv2.INTER_CUBIC,
|
||||
),
|
||||
NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5]),
|
||||
PrepareForNet(),
|
||||
lambda sample: torch.from_numpy(sample["image"]).unsqueeze(0),
|
||||
]
|
||||
)
|
||||
|
||||
transforms.levit_transform = Compose(
|
||||
[
|
||||
lambda img: {"image": img / 255.0},
|
||||
Resize(
|
||||
224,
|
||||
224,
|
||||
resize_target=None,
|
||||
keep_aspect_ratio=False,
|
||||
ensure_multiple_of=32,
|
||||
resize_method="minimal",
|
||||
image_interpolation_method=cv2.INTER_CUBIC,
|
||||
),
|
||||
NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5]),
|
||||
PrepareForNet(),
|
||||
lambda sample: torch.from_numpy(sample["image"]).unsqueeze(0),
|
||||
]
|
||||
)
|
||||
|
||||
return transforms
|
||||
@@ -0,0 +1,198 @@
|
||||
import types
|
||||
from typing import Optional
|
||||
|
||||
import numpy as np
|
||||
import timm
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from timm.models.beit import gen_relative_position_index
|
||||
from torch.utils.checkpoint import checkpoint
|
||||
|
||||
from .utils import forward_adapted_unflatten, make_backbone_default
|
||||
|
||||
|
||||
def forward_beit(pretrained, x):
|
||||
return forward_adapted_unflatten(pretrained, x, "forward_features")
|
||||
|
||||
|
||||
def patch_embed_forward(self, x):
|
||||
"""
|
||||
Modification of timm.models.layers.patch_embed.py: PatchEmbed.forward to support arbitrary window sizes.
|
||||
"""
|
||||
x = self.proj(x)
|
||||
if self.flatten:
|
||||
x = x.flatten(2).transpose(1, 2)
|
||||
x = self.norm(x)
|
||||
return x
|
||||
|
||||
|
||||
def _get_rel_pos_bias(self, window_size):
|
||||
"""
|
||||
Modification of timm.models.beit.py: Attention._get_rel_pos_bias to support arbitrary window sizes.
|
||||
"""
|
||||
old_height = 2 * self.window_size[0] - 1
|
||||
old_width = 2 * self.window_size[1] - 1
|
||||
|
||||
new_height = 2 * window_size[0] - 1
|
||||
new_width = 2 * window_size[1] - 1
|
||||
|
||||
old_relative_position_bias_table = self.relative_position_bias_table
|
||||
|
||||
old_num_relative_distance = self.num_relative_distance
|
||||
new_num_relative_distance = new_height * new_width + 3
|
||||
|
||||
old_sub_table = old_relative_position_bias_table[:old_num_relative_distance - 3]
|
||||
|
||||
old_sub_table = old_sub_table.reshape(1, old_width, old_height, -1).permute(0, 3, 1, 2)
|
||||
new_sub_table = F.interpolate(old_sub_table, size=(int(new_height), int(new_width)), mode="bilinear")
|
||||
new_sub_table = new_sub_table.permute(0, 2, 3, 1).reshape(new_num_relative_distance - 3, -1)
|
||||
|
||||
new_relative_position_bias_table = torch.cat(
|
||||
[new_sub_table, old_relative_position_bias_table[old_num_relative_distance - 3:]])
|
||||
|
||||
key = str(window_size[1]) + "," + str(window_size[0])
|
||||
if key not in self.relative_position_indices.keys():
|
||||
self.relative_position_indices[key] = gen_relative_position_index(window_size)
|
||||
|
||||
relative_position_bias = new_relative_position_bias_table[
|
||||
self.relative_position_indices[key].view(-1)].view(
|
||||
window_size[0] * window_size[1] + 1,
|
||||
window_size[0] * window_size[1] + 1, -1) # Wh*Ww,Wh*Ww,nH
|
||||
relative_position_bias = relative_position_bias.permute(2, 0, 1).contiguous() # nH, Wh*Ww, Wh*Ww
|
||||
return relative_position_bias.unsqueeze(0)
|
||||
|
||||
|
||||
def attention_forward(self, x, resolution, shared_rel_pos_bias: Optional[torch.Tensor] = None):
|
||||
"""
|
||||
Modification of timm.models.beit.py: Attention.forward to support arbitrary window sizes.
|
||||
"""
|
||||
B, N, C = x.shape
|
||||
|
||||
qkv_bias = torch.cat((self.q_bias, self.k_bias, self.v_bias)) if self.q_bias is not None else None
|
||||
qkv = F.linear(input=x, weight=self.qkv.weight, bias=qkv_bias)
|
||||
qkv = qkv.reshape(B, N, 3, self.num_heads, -1).permute(2, 0, 3, 1, 4)
|
||||
q, k, v = qkv.unbind(0) # make torchscript happy (cannot use tensor as tuple)
|
||||
|
||||
q = q * self.scale
|
||||
attn = (q @ k.transpose(-2, -1))
|
||||
|
||||
if self.relative_position_bias_table is not None:
|
||||
window_size = tuple(np.array(resolution) // 16)
|
||||
attn = attn + self._get_rel_pos_bias(window_size)
|
||||
if shared_rel_pos_bias is not None:
|
||||
attn = attn + shared_rel_pos_bias
|
||||
|
||||
attn = attn.softmax(dim=-1)
|
||||
attn = self.attn_drop(attn)
|
||||
|
||||
x = (attn @ v).transpose(1, 2).reshape(B, N, -1)
|
||||
x = self.proj(x)
|
||||
x = self.proj_drop(x)
|
||||
return x
|
||||
|
||||
|
||||
def block_forward(self, x, resolution, shared_rel_pos_bias: Optional[torch.Tensor] = None):
|
||||
"""
|
||||
Modification of timm.models.beit.py: Block.forward to support arbitrary window sizes.
|
||||
"""
|
||||
if hasattr(self, 'drop_path1') and not hasattr(self, 'drop_path'):
|
||||
self.drop_path = self.drop_path1
|
||||
if self.gamma_1 is None:
|
||||
x = x + self.drop_path(self.attn(self.norm1(x), resolution, shared_rel_pos_bias=shared_rel_pos_bias))
|
||||
x = x + self.drop_path(self.mlp(self.norm2(x)))
|
||||
else:
|
||||
x = x + self.drop_path(self.gamma_1 * self.attn(self.norm1(x), resolution,
|
||||
shared_rel_pos_bias=shared_rel_pos_bias))
|
||||
x = x + self.drop_path(self.gamma_2 * self.mlp(self.norm2(x)))
|
||||
return x
|
||||
|
||||
|
||||
def beit_forward_features(self, x):
|
||||
"""
|
||||
Modification of timm.models.beit.py: Beit.forward_features to support arbitrary window sizes.
|
||||
"""
|
||||
resolution = x.shape[2:]
|
||||
|
||||
x = self.patch_embed(x)
|
||||
x = torch.cat((self.cls_token.expand(x.shape[0], -1, -1), x), dim=1)
|
||||
if self.pos_embed is not None:
|
||||
x = x + self.pos_embed
|
||||
x = self.pos_drop(x)
|
||||
|
||||
rel_pos_bias = self.rel_pos_bias() if self.rel_pos_bias is not None else None
|
||||
for blk in self.blocks:
|
||||
if self.grad_checkpointing and not torch.jit.is_scripting():
|
||||
x = checkpoint(blk, x, shared_rel_pos_bias=rel_pos_bias)
|
||||
else:
|
||||
x = blk(x, resolution, shared_rel_pos_bias=rel_pos_bias)
|
||||
x = self.norm(x)
|
||||
return x
|
||||
|
||||
|
||||
def _make_beit_backbone(
|
||||
model,
|
||||
features=[96, 192, 384, 768],
|
||||
size=[384, 384],
|
||||
hooks=[0, 4, 8, 11],
|
||||
vit_features=768,
|
||||
use_readout="ignore",
|
||||
start_index=1,
|
||||
start_index_readout=1,
|
||||
):
|
||||
backbone = make_backbone_default(model, features, size, hooks, vit_features, use_readout, start_index,
|
||||
start_index_readout)
|
||||
|
||||
backbone.model.patch_embed.forward = types.MethodType(patch_embed_forward, backbone.model.patch_embed)
|
||||
backbone.model.forward_features = types.MethodType(beit_forward_features, backbone.model)
|
||||
|
||||
for block in backbone.model.blocks:
|
||||
attn = block.attn
|
||||
attn._get_rel_pos_bias = types.MethodType(_get_rel_pos_bias, attn)
|
||||
attn.forward = types.MethodType(attention_forward, attn)
|
||||
attn.relative_position_indices = {}
|
||||
|
||||
block.forward = types.MethodType(block_forward, block)
|
||||
|
||||
return backbone
|
||||
|
||||
|
||||
def _make_pretrained_beitl16_512(pretrained, use_readout="ignore", hooks=None):
|
||||
model = timm.create_model("beit_large_patch16_512", pretrained=pretrained)
|
||||
|
||||
hooks = [5, 11, 17, 23] if hooks is None else hooks
|
||||
|
||||
features = [256, 512, 1024, 1024]
|
||||
|
||||
return _make_beit_backbone(
|
||||
model,
|
||||
features=features,
|
||||
size=[512, 512],
|
||||
hooks=hooks,
|
||||
vit_features=1024,
|
||||
use_readout=use_readout,
|
||||
)
|
||||
|
||||
|
||||
def _make_pretrained_beitl16_384(pretrained, use_readout="ignore", hooks=None):
|
||||
model = timm.create_model("beit_large_patch16_384", pretrained=pretrained)
|
||||
|
||||
hooks = [5, 11, 17, 23] if hooks is None else hooks
|
||||
return _make_beit_backbone(
|
||||
model,
|
||||
features=[256, 512, 1024, 1024],
|
||||
hooks=hooks,
|
||||
vit_features=1024,
|
||||
use_readout=use_readout,
|
||||
)
|
||||
|
||||
|
||||
def _make_pretrained_beitb16_384(pretrained, use_readout="ignore", hooks=None):
|
||||
model = timm.create_model("beit_base_patch16_384", pretrained=pretrained)
|
||||
|
||||
hooks = [2, 5, 8, 11] if hooks is None else hooks
|
||||
return _make_beit_backbone(
|
||||
model,
|
||||
features=[96, 192, 384, 768],
|
||||
hooks=hooks,
|
||||
use_readout=use_readout,
|
||||
)
|
||||
@@ -0,0 +1,106 @@
|
||||
import numpy as np
|
||||
import timm
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
|
||||
from .utils import Transpose, activations, get_activation
|
||||
|
||||
|
||||
def forward_levit(pretrained, x):
|
||||
pretrained.model.forward_features(x)
|
||||
|
||||
layer_1 = pretrained.activations["1"]
|
||||
layer_2 = pretrained.activations["2"]
|
||||
layer_3 = pretrained.activations["3"]
|
||||
|
||||
layer_1 = pretrained.act_postprocess1(layer_1)
|
||||
layer_2 = pretrained.act_postprocess2(layer_2)
|
||||
layer_3 = pretrained.act_postprocess3(layer_3)
|
||||
|
||||
return layer_1, layer_2, layer_3
|
||||
|
||||
|
||||
def _make_levit_backbone(
|
||||
model,
|
||||
hooks=[3, 11, 21],
|
||||
patch_grid=[14, 14]
|
||||
):
|
||||
pretrained = nn.Module()
|
||||
|
||||
pretrained.model = model
|
||||
pretrained.model.blocks[hooks[0]].register_forward_hook(get_activation("1"))
|
||||
pretrained.model.blocks[hooks[1]].register_forward_hook(get_activation("2"))
|
||||
pretrained.model.blocks[hooks[2]].register_forward_hook(get_activation("3"))
|
||||
|
||||
pretrained.activations = activations
|
||||
|
||||
patch_grid_size = np.array(patch_grid, dtype=int)
|
||||
|
||||
pretrained.act_postprocess1 = nn.Sequential(
|
||||
Transpose(1, 2),
|
||||
nn.Unflatten(2, torch.Size(patch_grid_size.tolist()))
|
||||
)
|
||||
pretrained.act_postprocess2 = nn.Sequential(
|
||||
Transpose(1, 2),
|
||||
nn.Unflatten(2, torch.Size((np.ceil(patch_grid_size / 2).astype(int)).tolist()))
|
||||
)
|
||||
pretrained.act_postprocess3 = nn.Sequential(
|
||||
Transpose(1, 2),
|
||||
nn.Unflatten(2, torch.Size((np.ceil(patch_grid_size / 4).astype(int)).tolist()))
|
||||
)
|
||||
|
||||
return pretrained
|
||||
|
||||
|
||||
class ConvTransposeNorm(nn.Sequential):
|
||||
"""
|
||||
Modification of
|
||||
https://github.com/rwightman/pytorch-image-models/blob/master/timm/models/levit.py: ConvNorm
|
||||
such that ConvTranspose2d is used instead of Conv2d.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self, in_chs, out_chs, kernel_size=1, stride=1, pad=0, dilation=1,
|
||||
groups=1, bn_weight_init=1):
|
||||
super().__init__()
|
||||
self.add_module('c',
|
||||
nn.ConvTranspose2d(in_chs, out_chs, kernel_size, stride, pad, dilation, groups, bias=False))
|
||||
self.add_module('bn', nn.BatchNorm2d(out_chs))
|
||||
|
||||
nn.init.constant_(self.bn.weight, bn_weight_init)
|
||||
|
||||
@torch.no_grad()
|
||||
def fuse(self):
|
||||
c, bn = self._modules.values()
|
||||
w = bn.weight / (bn.running_var + bn.eps) ** 0.5
|
||||
w = c.weight * w[:, None, None, None]
|
||||
b = bn.bias - bn.running_mean * bn.weight / (bn.running_var + bn.eps) ** 0.5
|
||||
m = nn.ConvTranspose2d(
|
||||
w.size(1), w.size(0), w.shape[2:], stride=self.c.stride,
|
||||
padding=self.c.padding, dilation=self.c.dilation, groups=self.c.groups)
|
||||
m.weight.data.copy_(w)
|
||||
m.bias.data.copy_(b)
|
||||
return m
|
||||
|
||||
|
||||
def stem_b4_transpose(in_chs, out_chs, activation):
|
||||
"""
|
||||
Modification of
|
||||
https://github.com/rwightman/pytorch-image-models/blob/master/timm/models/levit.py: stem_b16
|
||||
such that ConvTranspose2d is used instead of Conv2d and stem is also reduced to the half.
|
||||
"""
|
||||
return nn.Sequential(
|
||||
ConvTransposeNorm(in_chs, out_chs, 3, 2, 1),
|
||||
activation(),
|
||||
ConvTransposeNorm(out_chs, out_chs // 2, 3, 2, 1),
|
||||
activation())
|
||||
|
||||
|
||||
def _make_pretrained_levit_384(pretrained, hooks=None):
|
||||
model = timm.create_model("levit_384", pretrained=pretrained)
|
||||
|
||||
hooks = [3, 11, 21] if hooks == None else hooks
|
||||
return _make_levit_backbone(
|
||||
model,
|
||||
hooks=hooks
|
||||
)
|
||||
@@ -0,0 +1,38 @@
|
||||
from pathlib import Path
|
||||
|
||||
import timm
|
||||
import torch.nn as nn
|
||||
|
||||
from ..external.next_vit.classification.nextvit import *
|
||||
from .utils import activations, forward_default, get_activation
|
||||
|
||||
|
||||
def forward_next_vit(pretrained, x):
|
||||
return forward_default(pretrained, x, "forward")
|
||||
|
||||
|
||||
def _make_next_vit_backbone(
|
||||
model,
|
||||
hooks=[2, 6, 36, 39],
|
||||
):
|
||||
pretrained = nn.Module()
|
||||
|
||||
pretrained.model = model
|
||||
pretrained.model.features[hooks[0]].register_forward_hook(get_activation("1"))
|
||||
pretrained.model.features[hooks[1]].register_forward_hook(get_activation("2"))
|
||||
pretrained.model.features[hooks[2]].register_forward_hook(get_activation("3"))
|
||||
pretrained.model.features[hooks[3]].register_forward_hook(get_activation("4"))
|
||||
|
||||
pretrained.activations = activations
|
||||
|
||||
return pretrained
|
||||
|
||||
|
||||
def _make_pretrained_next_vit_large_6m(hooks=None):
|
||||
model = timm.create_model("nextvit_large")
|
||||
|
||||
hooks = [2, 6, 36, 39] if hooks == None else hooks
|
||||
return _make_next_vit_backbone(
|
||||
model,
|
||||
hooks=hooks,
|
||||
)
|
||||
@@ -0,0 +1,13 @@
|
||||
import timm
|
||||
|
||||
from .swin_common import _make_swin_backbone
|
||||
|
||||
|
||||
def _make_pretrained_swinl12_384(pretrained, hooks=None):
|
||||
model = timm.create_model("swin_large_patch4_window12_384", pretrained=pretrained)
|
||||
|
||||
hooks = [1, 1, 17, 1] if hooks == None else hooks
|
||||
return _make_swin_backbone(
|
||||
model,
|
||||
hooks=hooks
|
||||
)
|
||||
@@ -0,0 +1,34 @@
|
||||
import timm
|
||||
|
||||
from .swin_common import _make_swin_backbone
|
||||
|
||||
|
||||
def _make_pretrained_swin2l24_384(pretrained, hooks=None):
|
||||
model = timm.create_model("swinv2_large_window12to24_192to384_22kft1k", pretrained=pretrained)
|
||||
|
||||
hooks = [1, 1, 17, 1] if hooks == None else hooks
|
||||
return _make_swin_backbone(
|
||||
model,
|
||||
hooks=hooks
|
||||
)
|
||||
|
||||
|
||||
def _make_pretrained_swin2b24_384(pretrained, hooks=None):
|
||||
model = timm.create_model("swinv2_base_window12to24_192to384_22kft1k", pretrained=pretrained)
|
||||
|
||||
hooks = [1, 1, 17, 1] if hooks == None else hooks
|
||||
return _make_swin_backbone(
|
||||
model,
|
||||
hooks=hooks
|
||||
)
|
||||
|
||||
|
||||
def _make_pretrained_swin2t16_256(pretrained, hooks=None):
|
||||
model = timm.create_model("swinv2_tiny_window16_256", pretrained=pretrained)
|
||||
|
||||
hooks = [1, 1, 5, 1] if hooks == None else hooks
|
||||
return _make_swin_backbone(
|
||||
model,
|
||||
hooks=hooks,
|
||||
patch_grid=[64, 64]
|
||||
)
|
||||
@@ -0,0 +1,51 @@
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
|
||||
from .utils import Transpose, activations, forward_default, get_activation
|
||||
|
||||
|
||||
def forward_swin(pretrained, x):
|
||||
return forward_default(pretrained, x)
|
||||
|
||||
|
||||
def _make_swin_backbone(
|
||||
model,
|
||||
hooks=[1, 1, 17, 1],
|
||||
patch_grid=[96, 96]
|
||||
):
|
||||
pretrained = nn.Module()
|
||||
|
||||
pretrained.model = model
|
||||
pretrained.model.layers[0].blocks[hooks[0]].register_forward_hook(get_activation("1"))
|
||||
pretrained.model.layers[1].blocks[hooks[1]].register_forward_hook(get_activation("2"))
|
||||
pretrained.model.layers[2].blocks[hooks[2]].register_forward_hook(get_activation("3"))
|
||||
pretrained.model.layers[3].blocks[hooks[3]].register_forward_hook(get_activation("4"))
|
||||
|
||||
pretrained.activations = activations
|
||||
|
||||
if hasattr(model, "patch_grid"):
|
||||
used_patch_grid = model.patch_grid
|
||||
else:
|
||||
used_patch_grid = patch_grid
|
||||
|
||||
patch_grid_size = np.array(used_patch_grid, dtype=int)
|
||||
|
||||
pretrained.act_postprocess1 = nn.Sequential(
|
||||
Transpose(1, 2),
|
||||
nn.Unflatten(2, torch.Size(patch_grid_size.tolist()))
|
||||
)
|
||||
pretrained.act_postprocess2 = nn.Sequential(
|
||||
Transpose(1, 2),
|
||||
nn.Unflatten(2, torch.Size((patch_grid_size // 2).tolist()))
|
||||
)
|
||||
pretrained.act_postprocess3 = nn.Sequential(
|
||||
Transpose(1, 2),
|
||||
nn.Unflatten(2, torch.Size((patch_grid_size // 4).tolist()))
|
||||
)
|
||||
pretrained.act_postprocess4 = nn.Sequential(
|
||||
Transpose(1, 2),
|
||||
nn.Unflatten(2, torch.Size((patch_grid_size // 8).tolist()))
|
||||
)
|
||||
|
||||
return pretrained
|
||||
@@ -0,0 +1,248 @@
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
|
||||
|
||||
class Slice(nn.Module):
|
||||
def __init__(self, start_index=1):
|
||||
super(Slice, self).__init__()
|
||||
self.start_index = start_index
|
||||
|
||||
def forward(self, x):
|
||||
return x[:, self.start_index:]
|
||||
|
||||
|
||||
class AddReadout(nn.Module):
|
||||
def __init__(self, start_index=1):
|
||||
super(AddReadout, self).__init__()
|
||||
self.start_index = start_index
|
||||
|
||||
def forward(self, x):
|
||||
if self.start_index == 2:
|
||||
readout = (x[:, 0] + x[:, 1]) / 2
|
||||
else:
|
||||
readout = x[:, 0]
|
||||
return x[:, self.start_index:] + readout.unsqueeze(1)
|
||||
|
||||
|
||||
class ProjectReadout(nn.Module):
|
||||
def __init__(self, in_features, start_index=1):
|
||||
super(ProjectReadout, self).__init__()
|
||||
self.start_index = start_index
|
||||
|
||||
self.project = nn.Sequential(nn.Linear(2 * in_features, in_features), nn.GELU())
|
||||
|
||||
def forward(self, x):
|
||||
readout = x[:, 0].unsqueeze(1).expand_as(x[:, self.start_index:])
|
||||
features = torch.cat((x[:, self.start_index:], readout), -1)
|
||||
|
||||
return self.project(features)
|
||||
|
||||
|
||||
class Transpose(nn.Module):
|
||||
def __init__(self, dim0, dim1):
|
||||
super(Transpose, self).__init__()
|
||||
self.dim0 = dim0
|
||||
self.dim1 = dim1
|
||||
|
||||
def forward(self, x):
|
||||
x = x.transpose(self.dim0, self.dim1)
|
||||
return x
|
||||
|
||||
|
||||
activations = {}
|
||||
|
||||
|
||||
def get_activation(name):
|
||||
def hook(model, input, output):
|
||||
activations[name] = output
|
||||
|
||||
return hook
|
||||
|
||||
|
||||
def forward_default(pretrained, x, function_name="forward_features"):
|
||||
exec(f"pretrained.model.{function_name}(x)")
|
||||
|
||||
layer_1 = pretrained.activations["1"]
|
||||
layer_2 = pretrained.activations["2"]
|
||||
layer_3 = pretrained.activations["3"]
|
||||
layer_4 = pretrained.activations["4"]
|
||||
|
||||
if hasattr(pretrained, "act_postprocess1"):
|
||||
layer_1 = pretrained.act_postprocess1(layer_1)
|
||||
if hasattr(pretrained, "act_postprocess2"):
|
||||
layer_2 = pretrained.act_postprocess2(layer_2)
|
||||
if hasattr(pretrained, "act_postprocess3"):
|
||||
layer_3 = pretrained.act_postprocess3(layer_3)
|
||||
if hasattr(pretrained, "act_postprocess4"):
|
||||
layer_4 = pretrained.act_postprocess4(layer_4)
|
||||
|
||||
return layer_1, layer_2, layer_3, layer_4
|
||||
|
||||
|
||||
def forward_adapted_unflatten(pretrained, x, function_name="forward_features"):
|
||||
b, c, h, w = x.shape
|
||||
|
||||
exec(f"glob = pretrained.model.{function_name}(x)")
|
||||
|
||||
layer_1 = pretrained.activations["1"]
|
||||
layer_2 = pretrained.activations["2"]
|
||||
layer_3 = pretrained.activations["3"]
|
||||
layer_4 = pretrained.activations["4"]
|
||||
|
||||
layer_1 = pretrained.act_postprocess1[0:2](layer_1)
|
||||
layer_2 = pretrained.act_postprocess2[0:2](layer_2)
|
||||
layer_3 = pretrained.act_postprocess3[0:2](layer_3)
|
||||
layer_4 = pretrained.act_postprocess4[0:2](layer_4)
|
||||
|
||||
unflatten = nn.Sequential(
|
||||
nn.Unflatten(
|
||||
2,
|
||||
torch.Size(
|
||||
[
|
||||
h // pretrained.model.patch_size[1],
|
||||
w // pretrained.model.patch_size[0],
|
||||
]
|
||||
),
|
||||
)
|
||||
)
|
||||
|
||||
if layer_1.ndim == 3:
|
||||
layer_1 = unflatten(layer_1)
|
||||
if layer_2.ndim == 3:
|
||||
layer_2 = unflatten(layer_2)
|
||||
if layer_3.ndim == 3:
|
||||
layer_3 = unflatten(layer_3)
|
||||
if layer_4.ndim == 3:
|
||||
layer_4 = unflatten(layer_4)
|
||||
|
||||
layer_1 = pretrained.act_postprocess1[3: len(pretrained.act_postprocess1)](layer_1)
|
||||
layer_2 = pretrained.act_postprocess2[3: len(pretrained.act_postprocess2)](layer_2)
|
||||
layer_3 = pretrained.act_postprocess3[3: len(pretrained.act_postprocess3)](layer_3)
|
||||
layer_4 = pretrained.act_postprocess4[3: len(pretrained.act_postprocess4)](layer_4)
|
||||
|
||||
return layer_1, layer_2, layer_3, layer_4
|
||||
|
||||
|
||||
def get_readout_oper(vit_features, features, use_readout, start_index=1):
|
||||
if use_readout == "ignore":
|
||||
readout_oper = [Slice(start_index)] * len(features)
|
||||
elif use_readout == "add":
|
||||
readout_oper = [AddReadout(start_index)] * len(features)
|
||||
elif use_readout == "project":
|
||||
readout_oper = [
|
||||
ProjectReadout(vit_features, start_index) for out_feat in features
|
||||
]
|
||||
else:
|
||||
assert (
|
||||
False
|
||||
), "wrong operation for readout token, use_readout can be 'ignore', 'add', or 'project'"
|
||||
|
||||
return readout_oper
|
||||
|
||||
|
||||
def make_backbone_default(
|
||||
model,
|
||||
features=[96, 192, 384, 768],
|
||||
size=[384, 384],
|
||||
hooks=[2, 5, 8, 11],
|
||||
vit_features=768,
|
||||
use_readout="ignore",
|
||||
start_index=1,
|
||||
start_index_readout=1,
|
||||
):
|
||||
pretrained = nn.Module()
|
||||
|
||||
pretrained.model = model
|
||||
pretrained.model.blocks[hooks[0]].register_forward_hook(get_activation("1"))
|
||||
pretrained.model.blocks[hooks[1]].register_forward_hook(get_activation("2"))
|
||||
pretrained.model.blocks[hooks[2]].register_forward_hook(get_activation("3"))
|
||||
pretrained.model.blocks[hooks[3]].register_forward_hook(get_activation("4"))
|
||||
|
||||
pretrained.activations = activations
|
||||
|
||||
readout_oper = get_readout_oper(vit_features, features, use_readout, start_index_readout)
|
||||
|
||||
# 32, 48, 136, 384
|
||||
pretrained.act_postprocess1 = nn.Sequential(
|
||||
readout_oper[0],
|
||||
Transpose(1, 2),
|
||||
nn.Unflatten(2, torch.Size([size[0] // 16, size[1] // 16])),
|
||||
nn.Conv2d(
|
||||
in_channels=vit_features,
|
||||
out_channels=features[0],
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0,
|
||||
),
|
||||
nn.ConvTranspose2d(
|
||||
in_channels=features[0],
|
||||
out_channels=features[0],
|
||||
kernel_size=4,
|
||||
stride=4,
|
||||
padding=0,
|
||||
bias=True,
|
||||
dilation=1,
|
||||
groups=1,
|
||||
),
|
||||
)
|
||||
|
||||
pretrained.act_postprocess2 = nn.Sequential(
|
||||
readout_oper[1],
|
||||
Transpose(1, 2),
|
||||
nn.Unflatten(2, torch.Size([size[0] // 16, size[1] // 16])),
|
||||
nn.Conv2d(
|
||||
in_channels=vit_features,
|
||||
out_channels=features[1],
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0,
|
||||
),
|
||||
nn.ConvTranspose2d(
|
||||
in_channels=features[1],
|
||||
out_channels=features[1],
|
||||
kernel_size=2,
|
||||
stride=2,
|
||||
padding=0,
|
||||
bias=True,
|
||||
dilation=1,
|
||||
groups=1,
|
||||
),
|
||||
)
|
||||
|
||||
pretrained.act_postprocess3 = nn.Sequential(
|
||||
readout_oper[2],
|
||||
Transpose(1, 2),
|
||||
nn.Unflatten(2, torch.Size([size[0] // 16, size[1] // 16])),
|
||||
nn.Conv2d(
|
||||
in_channels=vit_features,
|
||||
out_channels=features[2],
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0,
|
||||
),
|
||||
)
|
||||
|
||||
pretrained.act_postprocess4 = nn.Sequential(
|
||||
readout_oper[3],
|
||||
Transpose(1, 2),
|
||||
nn.Unflatten(2, torch.Size([size[0] // 16, size[1] // 16])),
|
||||
nn.Conv2d(
|
||||
in_channels=vit_features,
|
||||
out_channels=features[3],
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0,
|
||||
),
|
||||
nn.Conv2d(
|
||||
in_channels=features[3],
|
||||
out_channels=features[3],
|
||||
kernel_size=3,
|
||||
stride=2,
|
||||
padding=1,
|
||||
),
|
||||
)
|
||||
|
||||
pretrained.model.start_index = start_index
|
||||
pretrained.model.patch_size = [16, 16]
|
||||
|
||||
return pretrained
|
||||
@@ -0,0 +1,222 @@
|
||||
import math
|
||||
import types
|
||||
|
||||
import timm
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
|
||||
from .utils import (Transpose, activations, forward_adapted_unflatten,
|
||||
get_activation, get_readout_oper, make_backbone_default)
|
||||
|
||||
|
||||
def forward_vit(pretrained, x):
|
||||
return forward_adapted_unflatten(pretrained, x, "forward_flex")
|
||||
|
||||
|
||||
def _resize_pos_embed(self, posemb, gs_h, gs_w):
|
||||
posemb_tok, posemb_grid = (
|
||||
posemb[:, : self.start_index],
|
||||
posemb[0, self.start_index:],
|
||||
)
|
||||
|
||||
gs_old = int(math.sqrt(len(posemb_grid)))
|
||||
|
||||
posemb_grid = posemb_grid.reshape(1, gs_old, gs_old, -1).permute(0, 3, 1, 2)
|
||||
posemb_grid = F.interpolate(posemb_grid, size=(gs_h, gs_w), mode="bilinear")
|
||||
posemb_grid = posemb_grid.permute(0, 2, 3, 1).reshape(1, gs_h * gs_w, -1)
|
||||
|
||||
posemb = torch.cat([posemb_tok, posemb_grid], dim=1)
|
||||
|
||||
return posemb
|
||||
|
||||
|
||||
def forward_flex(self, x):
|
||||
b, c, h, w = x.shape
|
||||
|
||||
pos_embed = self._resize_pos_embed(
|
||||
self.pos_embed, h // self.patch_size[1], w // self.patch_size[0]
|
||||
)
|
||||
|
||||
B = x.shape[0]
|
||||
|
||||
if hasattr(self.patch_embed, "backbone"):
|
||||
x = self.patch_embed.backbone(x)
|
||||
if isinstance(x, (list, tuple)):
|
||||
x = x[-1] # last feature if backbone outputs list/tuple of features
|
||||
|
||||
x = self.patch_embed.proj(x).flatten(2).transpose(1, 2)
|
||||
|
||||
if getattr(self, "dist_token", None) is not None:
|
||||
cls_tokens = self.cls_token.expand(
|
||||
B, -1, -1
|
||||
) # stole cls_tokens impl from Phil Wang, thanks
|
||||
dist_token = self.dist_token.expand(B, -1, -1)
|
||||
x = torch.cat((cls_tokens, dist_token, x), dim=1)
|
||||
else:
|
||||
if self.no_embed_class:
|
||||
x = x + pos_embed
|
||||
cls_tokens = self.cls_token.expand(
|
||||
B, -1, -1
|
||||
) # stole cls_tokens impl from Phil Wang, thanks
|
||||
x = torch.cat((cls_tokens, x), dim=1)
|
||||
|
||||
if not self.no_embed_class:
|
||||
x = x + pos_embed
|
||||
x = self.pos_drop(x)
|
||||
|
||||
for blk in self.blocks:
|
||||
x = blk(x)
|
||||
|
||||
x = self.norm(x)
|
||||
|
||||
return x
|
||||
|
||||
|
||||
def _make_vit_b16_backbone(
|
||||
model,
|
||||
features=[96, 192, 384, 768],
|
||||
size=[384, 384],
|
||||
hooks=[2, 5, 8, 11],
|
||||
vit_features=768,
|
||||
use_readout="ignore",
|
||||
start_index=1,
|
||||
start_index_readout=1,
|
||||
):
|
||||
pretrained = make_backbone_default(model, features, size, hooks, vit_features, use_readout, start_index,
|
||||
start_index_readout)
|
||||
|
||||
# We inject this function into the VisionTransformer instances so that
|
||||
# we can use it with interpolated position embeddings without modifying the library source.
|
||||
pretrained.model.forward_flex = types.MethodType(forward_flex, pretrained.model)
|
||||
pretrained.model._resize_pos_embed = types.MethodType(
|
||||
_resize_pos_embed, pretrained.model
|
||||
)
|
||||
|
||||
return pretrained
|
||||
|
||||
|
||||
def _make_pretrained_vitl16_384(pretrained, use_readout="ignore", hooks=None):
|
||||
model = timm.create_model("vit_large_patch16_384", pretrained=pretrained)
|
||||
|
||||
hooks = [5, 11, 17, 23] if hooks == None else hooks
|
||||
return _make_vit_b16_backbone(
|
||||
model,
|
||||
features=[256, 512, 1024, 1024],
|
||||
hooks=hooks,
|
||||
vit_features=1024,
|
||||
use_readout=use_readout,
|
||||
)
|
||||
|
||||
|
||||
def _make_pretrained_vitb16_384(pretrained, use_readout="ignore", hooks=None):
|
||||
model = timm.create_model("vit_base_patch16_384", pretrained=pretrained)
|
||||
|
||||
hooks = [2, 5, 8, 11] if hooks == None else hooks
|
||||
return _make_vit_b16_backbone(
|
||||
model, features=[96, 192, 384, 768], hooks=hooks, use_readout=use_readout
|
||||
)
|
||||
|
||||
|
||||
def _make_vit_b_rn50_backbone(
|
||||
model,
|
||||
features=[256, 512, 768, 768],
|
||||
size=[384, 384],
|
||||
hooks=[0, 1, 8, 11],
|
||||
vit_features=768,
|
||||
patch_size=[16, 16],
|
||||
number_stages=2,
|
||||
use_vit_only=False,
|
||||
use_readout="ignore",
|
||||
start_index=1,
|
||||
):
|
||||
pretrained = nn.Module()
|
||||
|
||||
pretrained.model = model
|
||||
|
||||
used_number_stages = 0 if use_vit_only else number_stages
|
||||
for s in range(used_number_stages):
|
||||
pretrained.model.patch_embed.backbone.stages[s].register_forward_hook(
|
||||
get_activation(str(s + 1))
|
||||
)
|
||||
for s in range(used_number_stages, 4):
|
||||
pretrained.model.blocks[hooks[s]].register_forward_hook(get_activation(str(s + 1)))
|
||||
|
||||
pretrained.activations = activations
|
||||
|
||||
readout_oper = get_readout_oper(vit_features, features, use_readout, start_index)
|
||||
|
||||
for s in range(used_number_stages):
|
||||
value = nn.Sequential(nn.Identity(), nn.Identity(), nn.Identity())
|
||||
exec(f"pretrained.act_postprocess{s + 1}=value")
|
||||
for s in range(used_number_stages, 4):
|
||||
if s < number_stages:
|
||||
final_layer = nn.ConvTranspose2d(
|
||||
in_channels=features[s],
|
||||
out_channels=features[s],
|
||||
kernel_size=4 // (2 ** s),
|
||||
stride=4 // (2 ** s),
|
||||
padding=0,
|
||||
bias=True,
|
||||
dilation=1,
|
||||
groups=1,
|
||||
)
|
||||
elif s > number_stages:
|
||||
final_layer = nn.Conv2d(
|
||||
in_channels=features[3],
|
||||
out_channels=features[3],
|
||||
kernel_size=3,
|
||||
stride=2,
|
||||
padding=1,
|
||||
)
|
||||
else:
|
||||
final_layer = None
|
||||
|
||||
layers = [
|
||||
readout_oper[s],
|
||||
Transpose(1, 2),
|
||||
nn.Unflatten(2, torch.Size([size[0] // 16, size[1] // 16])),
|
||||
nn.Conv2d(
|
||||
in_channels=vit_features,
|
||||
out_channels=features[s],
|
||||
kernel_size=1,
|
||||
stride=1,
|
||||
padding=0,
|
||||
),
|
||||
]
|
||||
if final_layer is not None:
|
||||
layers.append(final_layer)
|
||||
|
||||
value = nn.Sequential(*layers)
|
||||
exec(f"pretrained.act_postprocess{s + 1}=value")
|
||||
|
||||
pretrained.model.start_index = start_index
|
||||
pretrained.model.patch_size = patch_size
|
||||
|
||||
# We inject this function into the VisionTransformer instances so that
|
||||
# we can use it with interpolated position embeddings without modifying the library source.
|
||||
pretrained.model.forward_flex = types.MethodType(forward_flex, pretrained.model)
|
||||
|
||||
# We inject this function into the VisionTransformer instances so that
|
||||
# we can use it with interpolated position embeddings without modifying the library source.
|
||||
pretrained.model._resize_pos_embed = types.MethodType(
|
||||
_resize_pos_embed, pretrained.model
|
||||
)
|
||||
|
||||
return pretrained
|
||||
|
||||
|
||||
def _make_pretrained_vitb_rn50_384(
|
||||
pretrained, use_readout="ignore", hooks=None, use_vit_only=False
|
||||
):
|
||||
model = timm.create_model("vit_base_resnet50_384", pretrained=pretrained)
|
||||
|
||||
hooks = [0, 1, 8, 11] if hooks == None else hooks
|
||||
return _make_vit_b_rn50_backbone(
|
||||
model,
|
||||
features=[256, 512, 768, 768],
|
||||
size=[384, 384],
|
||||
hooks=hooks,
|
||||
use_vit_only=use_vit_only,
|
||||
use_readout=use_readout,
|
||||
)
|
||||
@@ -0,0 +1,16 @@
|
||||
import torch
|
||||
|
||||
|
||||
class BaseModel(torch.nn.Module):
|
||||
def load(self, path):
|
||||
"""Load model from file.
|
||||
|
||||
Args:
|
||||
path (str): file path
|
||||
"""
|
||||
parameters = torch.load(path, map_location=torch.device('cpu'))
|
||||
|
||||
if "optimizer" in parameters:
|
||||
parameters = parameters["model"]
|
||||
|
||||
self.load_state_dict(parameters)
|
||||
@@ -0,0 +1,425 @@
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
|
||||
from .backbones.beit import (_make_pretrained_beitb16_384,
|
||||
_make_pretrained_beitl16_384,
|
||||
_make_pretrained_beitl16_512, forward_beit)
|
||||
from .backbones.levit import _make_pretrained_levit_384, forward_levit
|
||||
from .backbones.swin import _make_pretrained_swinl12_384
|
||||
from .backbones.swin2 import (_make_pretrained_swin2b24_384,
|
||||
_make_pretrained_swin2l24_384,
|
||||
_make_pretrained_swin2t16_256)
|
||||
from .backbones.swin_common import forward_swin
|
||||
from .backbones.vit import (_make_pretrained_vitb16_384,
|
||||
_make_pretrained_vitb_rn50_384,
|
||||
_make_pretrained_vitl16_384, forward_vit)
|
||||
|
||||
|
||||
def _make_encoder(backbone, features, use_pretrained, groups=1, expand=False, exportable=True, hooks=None,
|
||||
use_vit_only=False, use_readout="ignore", in_features=[96, 256, 512, 1024]):
|
||||
if backbone == "beitl16_512":
|
||||
pretrained = _make_pretrained_beitl16_512(
|
||||
use_pretrained, hooks=hooks, use_readout=use_readout
|
||||
)
|
||||
scratch = _make_scratch(
|
||||
[256, 512, 1024, 1024], features, groups=groups, expand=expand
|
||||
) # BEiT_512-L (backbone)
|
||||
elif backbone == "beitl16_384":
|
||||
pretrained = _make_pretrained_beitl16_384(
|
||||
use_pretrained, hooks=hooks, use_readout=use_readout
|
||||
)
|
||||
scratch = _make_scratch(
|
||||
[256, 512, 1024, 1024], features, groups=groups, expand=expand
|
||||
) # BEiT_384-L (backbone)
|
||||
elif backbone == "beitb16_384":
|
||||
pretrained = _make_pretrained_beitb16_384(
|
||||
use_pretrained, hooks=hooks, use_readout=use_readout
|
||||
)
|
||||
scratch = _make_scratch(
|
||||
[96, 192, 384, 768], features, groups=groups, expand=expand
|
||||
) # BEiT_384-B (backbone)
|
||||
elif backbone == "swin2l24_384":
|
||||
pretrained = _make_pretrained_swin2l24_384(
|
||||
use_pretrained, hooks=hooks
|
||||
)
|
||||
scratch = _make_scratch(
|
||||
[192, 384, 768, 1536], features, groups=groups, expand=expand
|
||||
) # Swin2-L/12to24 (backbone)
|
||||
elif backbone == "swin2b24_384":
|
||||
pretrained = _make_pretrained_swin2b24_384(
|
||||
use_pretrained, hooks=hooks
|
||||
)
|
||||
scratch = _make_scratch(
|
||||
[128, 256, 512, 1024], features, groups=groups, expand=expand
|
||||
) # Swin2-B/12to24 (backbone)
|
||||
elif backbone == "swin2t16_256":
|
||||
pretrained = _make_pretrained_swin2t16_256(
|
||||
use_pretrained, hooks=hooks
|
||||
)
|
||||
scratch = _make_scratch(
|
||||
[96, 192, 384, 768], features, groups=groups, expand=expand
|
||||
) # Swin2-T/16 (backbone)
|
||||
elif backbone == "swinl12_384":
|
||||
pretrained = _make_pretrained_swinl12_384(
|
||||
use_pretrained, hooks=hooks
|
||||
)
|
||||
scratch = _make_scratch(
|
||||
[192, 384, 768, 1536], features, groups=groups, expand=expand
|
||||
) # Swin-L/12 (backbone)
|
||||
elif backbone == "next_vit_large_6m":
|
||||
from .backbones.next_vit import _make_pretrained_next_vit_large_6m
|
||||
pretrained = _make_pretrained_next_vit_large_6m(hooks=hooks)
|
||||
scratch = _make_scratch(
|
||||
in_features, features, groups=groups, expand=expand
|
||||
) # Next-ViT-L on ImageNet-1K-6M (backbone)
|
||||
elif backbone == "levit_384":
|
||||
pretrained = _make_pretrained_levit_384(
|
||||
use_pretrained, hooks=hooks
|
||||
)
|
||||
scratch = _make_scratch(
|
||||
[384, 512, 768], features, groups=groups, expand=expand
|
||||
) # LeViT 384 (backbone)
|
||||
elif backbone == "vitl16_384":
|
||||
pretrained = _make_pretrained_vitl16_384(
|
||||
use_pretrained, hooks=hooks, use_readout=use_readout
|
||||
)
|
||||
scratch = _make_scratch(
|
||||
[256, 512, 1024, 1024], features, groups=groups, expand=expand
|
||||
) # ViT-L/16 - 85.0% Top1 (backbone)
|
||||
elif backbone == "vitb_rn50_384":
|
||||
pretrained = _make_pretrained_vitb_rn50_384(
|
||||
use_pretrained,
|
||||
hooks=hooks,
|
||||
use_vit_only=use_vit_only,
|
||||
use_readout=use_readout,
|
||||
)
|
||||
scratch = _make_scratch(
|
||||
[256, 512, 768, 768], features, groups=groups, expand=expand
|
||||
) # ViT-H/16 - 85.0% Top1 (backbone)
|
||||
elif backbone == "vitb16_384":
|
||||
pretrained = _make_pretrained_vitb16_384(
|
||||
use_pretrained, hooks=hooks, use_readout=use_readout
|
||||
)
|
||||
scratch = _make_scratch(
|
||||
[96, 192, 384, 768], features, groups=groups, expand=expand
|
||||
) # ViT-B/16 - 84.6% Top1 (backbone)
|
||||
elif backbone == "resnext101_wsl":
|
||||
pretrained = _make_pretrained_resnext101_wsl(use_pretrained)
|
||||
scratch = _make_scratch([256, 512, 1024, 2048], features, groups=groups, expand=expand) # efficientnet_lite3
|
||||
elif backbone == "efficientnet_lite3":
|
||||
pretrained = _make_pretrained_efficientnet_lite3(use_pretrained, exportable=exportable)
|
||||
scratch = _make_scratch([32, 48, 136, 384], features, groups=groups, expand=expand) # efficientnet_lite3
|
||||
else:
|
||||
print(f"Backbone '{backbone}' not implemented")
|
||||
assert False
|
||||
|
||||
return pretrained, scratch
|
||||
|
||||
|
||||
def _make_scratch(in_shape, out_shape, groups=1, expand=False):
|
||||
scratch = nn.Module()
|
||||
|
||||
out_shape1 = out_shape
|
||||
out_shape2 = out_shape
|
||||
out_shape3 = out_shape
|
||||
if len(in_shape) >= 4:
|
||||
out_shape4 = out_shape
|
||||
|
||||
if expand:
|
||||
out_shape1 = out_shape
|
||||
out_shape2 = out_shape*2
|
||||
out_shape3 = out_shape*4
|
||||
if len(in_shape) >= 4:
|
||||
out_shape4 = out_shape*8
|
||||
|
||||
scratch.layer1_rn = nn.Conv2d(
|
||||
in_shape[0], out_shape1, kernel_size=3, stride=1, padding=1, bias=False, groups=groups
|
||||
)
|
||||
scratch.layer2_rn = nn.Conv2d(
|
||||
in_shape[1], out_shape2, kernel_size=3, stride=1, padding=1, bias=False, groups=groups
|
||||
)
|
||||
scratch.layer3_rn = nn.Conv2d(
|
||||
in_shape[2], out_shape3, kernel_size=3, stride=1, padding=1, bias=False, groups=groups
|
||||
)
|
||||
if len(in_shape) >= 4:
|
||||
scratch.layer4_rn = nn.Conv2d(
|
||||
in_shape[3], out_shape4, kernel_size=3, stride=1, padding=1, bias=False, groups=groups
|
||||
)
|
||||
|
||||
return scratch
|
||||
|
||||
|
||||
def _make_pretrained_efficientnet_lite3(use_pretrained, exportable=False):
|
||||
efficientnet = torch.hub.load(
|
||||
"rwightman/gen-efficientnet-pytorch",
|
||||
"tf_efficientnet_lite3",
|
||||
pretrained=use_pretrained,
|
||||
exportable=exportable
|
||||
)
|
||||
return _make_efficientnet_backbone(efficientnet)
|
||||
|
||||
|
||||
def _make_efficientnet_backbone(effnet):
|
||||
pretrained = nn.Module()
|
||||
|
||||
pretrained.layer1 = nn.Sequential(
|
||||
effnet.conv_stem, effnet.bn1, effnet.act1, *effnet.blocks[0:2]
|
||||
)
|
||||
pretrained.layer2 = nn.Sequential(*effnet.blocks[2:3])
|
||||
pretrained.layer3 = nn.Sequential(*effnet.blocks[3:5])
|
||||
pretrained.layer4 = nn.Sequential(*effnet.blocks[5:9])
|
||||
|
||||
return pretrained
|
||||
|
||||
|
||||
def _make_resnet_backbone(resnet):
|
||||
pretrained = nn.Module()
|
||||
pretrained.layer1 = nn.Sequential(
|
||||
resnet.conv1, resnet.bn1, resnet.relu, resnet.maxpool, resnet.layer1
|
||||
)
|
||||
|
||||
pretrained.layer2 = resnet.layer2
|
||||
pretrained.layer3 = resnet.layer3
|
||||
pretrained.layer4 = resnet.layer4
|
||||
|
||||
return pretrained
|
||||
|
||||
|
||||
def _make_pretrained_resnext101_wsl(use_pretrained):
|
||||
resnet = torch.hub.load("facebookresearch/WSL-Images", "resnext101_32x8d_wsl")
|
||||
return _make_resnet_backbone(resnet)
|
||||
|
||||
|
||||
|
||||
class Interpolate(nn.Module):
|
||||
"""Interpolation module.
|
||||
"""
|
||||
|
||||
def __init__(self, scale_factor, mode, align_corners=False):
|
||||
"""Init.
|
||||
|
||||
Args:
|
||||
scale_factor (float): scaling
|
||||
mode (str): interpolation mode
|
||||
"""
|
||||
super(Interpolate, self).__init__()
|
||||
|
||||
self.interp = nn.functional.interpolate
|
||||
self.scale_factor = scale_factor
|
||||
self.mode = mode
|
||||
self.align_corners = align_corners
|
||||
|
||||
def forward(self, x):
|
||||
"""Forward pass.
|
||||
|
||||
Args:
|
||||
x (tensor): input
|
||||
|
||||
Returns:
|
||||
tensor: interpolated data
|
||||
"""
|
||||
|
||||
x = self.interp(
|
||||
x, scale_factor=self.scale_factor, mode=self.mode, align_corners=self.align_corners
|
||||
)
|
||||
|
||||
return x
|
||||
|
||||
|
||||
class ResidualConvUnit(nn.Module):
|
||||
"""Residual convolution module.
|
||||
"""
|
||||
|
||||
def __init__(self, features):
|
||||
"""Init.
|
||||
|
||||
Args:
|
||||
features (int): number of features
|
||||
"""
|
||||
super().__init__()
|
||||
|
||||
self.conv1 = nn.Conv2d(
|
||||
features, features, kernel_size=3, stride=1, padding=1, bias=True
|
||||
)
|
||||
|
||||
self.conv2 = nn.Conv2d(
|
||||
features, features, kernel_size=3, stride=1, padding=1, bias=True
|
||||
)
|
||||
|
||||
self.relu = nn.ReLU(inplace=True)
|
||||
|
||||
def forward(self, x):
|
||||
"""Forward pass.
|
||||
|
||||
Args:
|
||||
x (tensor): input
|
||||
|
||||
Returns:
|
||||
tensor: output
|
||||
"""
|
||||
out = self.relu(x)
|
||||
out = self.conv1(out)
|
||||
out = self.relu(out)
|
||||
out = self.conv2(out)
|
||||
|
||||
return out + x
|
||||
|
||||
|
||||
class FeatureFusionBlock(nn.Module):
|
||||
"""Feature fusion block.
|
||||
"""
|
||||
|
||||
def __init__(self, features):
|
||||
"""Init.
|
||||
|
||||
Args:
|
||||
features (int): number of features
|
||||
"""
|
||||
super(FeatureFusionBlock, self).__init__()
|
||||
|
||||
self.resConfUnit1 = ResidualConvUnit(features)
|
||||
self.resConfUnit2 = ResidualConvUnit(features)
|
||||
|
||||
def forward(self, *xs):
|
||||
"""Forward pass.
|
||||
|
||||
Returns:
|
||||
tensor: output
|
||||
"""
|
||||
output = xs[0]
|
||||
|
||||
if len(xs) == 2:
|
||||
output += self.resConfUnit1(xs[1])
|
||||
|
||||
output = self.resConfUnit2(output)
|
||||
|
||||
output = nn.functional.interpolate(
|
||||
output, scale_factor=2, mode="bilinear", align_corners=True
|
||||
)
|
||||
|
||||
return output
|
||||
|
||||
|
||||
|
||||
|
||||
class ResidualConvUnit_custom(nn.Module):
|
||||
"""Residual convolution module.
|
||||
"""
|
||||
|
||||
def __init__(self, features, activation, bn):
|
||||
"""Init.
|
||||
|
||||
Args:
|
||||
features (int): number of features
|
||||
"""
|
||||
super().__init__()
|
||||
|
||||
self.bn = bn
|
||||
|
||||
self.groups=1
|
||||
|
||||
self.conv1 = nn.Conv2d(
|
||||
features, features, kernel_size=3, stride=1, padding=1, bias=True, groups=self.groups
|
||||
)
|
||||
|
||||
self.conv2 = nn.Conv2d(
|
||||
features, features, kernel_size=3, stride=1, padding=1, bias=True, groups=self.groups
|
||||
)
|
||||
|
||||
if self.bn==True:
|
||||
self.bn1 = nn.BatchNorm2d(features)
|
||||
self.bn2 = nn.BatchNorm2d(features)
|
||||
|
||||
self.activation = activation
|
||||
|
||||
self.skip_add = nn.quantized.FloatFunctional()
|
||||
|
||||
def forward(self, x):
|
||||
"""Forward pass.
|
||||
|
||||
Args:
|
||||
x (tensor): input
|
||||
|
||||
Returns:
|
||||
tensor: output
|
||||
"""
|
||||
|
||||
out = self.activation(x)
|
||||
out = self.conv1(out)
|
||||
if self.bn==True:
|
||||
out = self.bn1(out)
|
||||
|
||||
out = self.activation(out)
|
||||
out = self.conv2(out)
|
||||
if self.bn==True:
|
||||
out = self.bn2(out)
|
||||
|
||||
if self.groups > 1:
|
||||
out = self.conv_merge(out)
|
||||
|
||||
return self.skip_add.add(out, x)
|
||||
|
||||
# return out + x
|
||||
|
||||
|
||||
class FeatureFusionBlock_custom(nn.Module):
|
||||
"""Feature fusion block.
|
||||
"""
|
||||
|
||||
def __init__(self, features, activation, deconv=False, bn=False, expand=False, align_corners=True, size=None):
|
||||
"""Init.
|
||||
|
||||
Args:
|
||||
features (int): number of features
|
||||
"""
|
||||
super(FeatureFusionBlock_custom, self).__init__()
|
||||
|
||||
self.deconv = deconv
|
||||
self.align_corners = align_corners
|
||||
|
||||
self.groups=1
|
||||
|
||||
self.expand = expand
|
||||
out_features = features
|
||||
if self.expand==True:
|
||||
out_features = features//2
|
||||
|
||||
self.out_conv = nn.Conv2d(features, out_features, kernel_size=1, stride=1, padding=0, bias=True, groups=1)
|
||||
|
||||
self.resConfUnit1 = ResidualConvUnit_custom(features, activation, bn)
|
||||
self.resConfUnit2 = ResidualConvUnit_custom(features, activation, bn)
|
||||
|
||||
self.skip_add = nn.quantized.FloatFunctional()
|
||||
|
||||
self.size=size
|
||||
|
||||
def forward(self, *xs, size=None):
|
||||
"""Forward pass.
|
||||
|
||||
Returns:
|
||||
tensor: output
|
||||
"""
|
||||
output = xs[0]
|
||||
|
||||
if len(xs) == 2:
|
||||
res = self.resConfUnit1(xs[1])
|
||||
output = self.skip_add.add(output, res)
|
||||
# output += res
|
||||
|
||||
output = self.resConfUnit2(output)
|
||||
|
||||
if (size is None) and (self.size is None):
|
||||
modifier = {"scale_factor": 2}
|
||||
elif size is None:
|
||||
modifier = {"size": self.size}
|
||||
else:
|
||||
modifier = {"size": size}
|
||||
|
||||
output = nn.functional.interpolate(
|
||||
output, **modifier, mode="bilinear", align_corners=self.align_corners
|
||||
)
|
||||
|
||||
output = self.out_conv(output)
|
||||
|
||||
return output
|
||||
|
||||
@@ -0,0 +1,159 @@
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from timm.models.layers import get_act_layer
|
||||
|
||||
from .backbones.levit import stem_b4_transpose
|
||||
from .base_model import BaseModel
|
||||
from .blocks import (FeatureFusionBlock_custom, Interpolate, _make_encoder,
|
||||
forward_beit, forward_levit, forward_swin, forward_vit)
|
||||
|
||||
|
||||
def _make_fusion_block(features, use_bn, size = None):
|
||||
return FeatureFusionBlock_custom(
|
||||
features,
|
||||
nn.ReLU(False),
|
||||
deconv=False,
|
||||
bn=use_bn,
|
||||
expand=False,
|
||||
align_corners=True,
|
||||
size=size,
|
||||
)
|
||||
|
||||
|
||||
class DPT(BaseModel):
|
||||
def __init__(
|
||||
self,
|
||||
head,
|
||||
features=256,
|
||||
backbone="vitb_rn50_384",
|
||||
readout="project",
|
||||
channels_last=False,
|
||||
use_bn=False,
|
||||
**kwargs
|
||||
):
|
||||
|
||||
super(DPT, self).__init__()
|
||||
|
||||
self.channels_last = channels_last
|
||||
|
||||
# For the Swin, Swin 2, LeViT and Next-ViT Transformers, the hierarchical architectures prevent setting the
|
||||
# hooks freely. Instead, the hooks have to be chosen according to the ranges specified in the comments.
|
||||
hooks = {
|
||||
"beitl16_512": [5, 11, 17, 23],
|
||||
"beitl16_384": [5, 11, 17, 23],
|
||||
"beitb16_384": [2, 5, 8, 11],
|
||||
"swin2l24_384": [1, 1, 17, 1], # Allowed ranges: [0, 1], [0, 1], [ 0, 17], [ 0, 1]
|
||||
"swin2b24_384": [1, 1, 17, 1], # [0, 1], [0, 1], [ 0, 17], [ 0, 1]
|
||||
"swin2t16_256": [1, 1, 5, 1], # [0, 1], [0, 1], [ 0, 5], [ 0, 1]
|
||||
"swinl12_384": [1, 1, 17, 1], # [0, 1], [0, 1], [ 0, 17], [ 0, 1]
|
||||
"next_vit_large_6m": [2, 6, 36, 39], # [0, 2], [3, 6], [ 7, 36], [37, 39]
|
||||
"levit_384": [3, 11, 21], # [0, 3], [6, 11], [14, 21]
|
||||
"vitb_rn50_384": [0, 1, 8, 11],
|
||||
"vitb16_384": [2, 5, 8, 11],
|
||||
"vitl16_384": [5, 11, 17, 23],
|
||||
}[backbone]
|
||||
|
||||
if "next_vit" in backbone:
|
||||
in_features = {
|
||||
"next_vit_large_6m": [96, 256, 512, 1024],
|
||||
}[backbone]
|
||||
else:
|
||||
in_features = None
|
||||
|
||||
# Instantiate backbone and reassemble blocks
|
||||
self.pretrained, self.scratch = _make_encoder(
|
||||
backbone,
|
||||
features,
|
||||
False, # Set to true of you want to train from scratch, uses ImageNet weights
|
||||
groups=1,
|
||||
expand=False,
|
||||
exportable=False,
|
||||
hooks=hooks,
|
||||
use_readout=readout,
|
||||
in_features=in_features,
|
||||
)
|
||||
|
||||
self.number_layers = len(hooks) if hooks is not None else 4
|
||||
size_refinenet3 = None
|
||||
self.scratch.stem_transpose = None
|
||||
|
||||
if "beit" in backbone:
|
||||
self.forward_transformer = forward_beit
|
||||
elif "swin" in backbone:
|
||||
self.forward_transformer = forward_swin
|
||||
elif "next_vit" in backbone:
|
||||
from .backbones.next_vit import forward_next_vit
|
||||
self.forward_transformer = forward_next_vit
|
||||
elif "levit" in backbone:
|
||||
self.forward_transformer = forward_levit
|
||||
size_refinenet3 = 7
|
||||
self.scratch.stem_transpose = stem_b4_transpose(256, 128, get_act_layer("hard_swish"))
|
||||
else:
|
||||
self.forward_transformer = forward_vit
|
||||
|
||||
self.scratch.refinenet1 = _make_fusion_block(features, use_bn)
|
||||
self.scratch.refinenet2 = _make_fusion_block(features, use_bn)
|
||||
self.scratch.refinenet3 = _make_fusion_block(features, use_bn, size_refinenet3)
|
||||
if self.number_layers >= 4:
|
||||
self.scratch.refinenet4 = _make_fusion_block(features, use_bn)
|
||||
|
||||
self.scratch.output_conv = head
|
||||
|
||||
|
||||
def forward(self, x):
|
||||
if self.channels_last == True:
|
||||
x.contiguous(memory_format=torch.channels_last)
|
||||
|
||||
layers = self.forward_transformer(self.pretrained, x)
|
||||
if self.number_layers == 3:
|
||||
layer_1, layer_2, layer_3 = layers
|
||||
else:
|
||||
layer_1, layer_2, layer_3, layer_4 = layers
|
||||
|
||||
layer_1_rn = self.scratch.layer1_rn(layer_1)
|
||||
layer_2_rn = self.scratch.layer2_rn(layer_2)
|
||||
layer_3_rn = self.scratch.layer3_rn(layer_3)
|
||||
if self.number_layers >= 4:
|
||||
layer_4_rn = self.scratch.layer4_rn(layer_4)
|
||||
|
||||
if self.number_layers == 3:
|
||||
path_3 = self.scratch.refinenet3(layer_3_rn, size=layer_2_rn.shape[2:])
|
||||
else:
|
||||
path_4 = self.scratch.refinenet4(layer_4_rn, size=layer_3_rn.shape[2:])
|
||||
path_3 = self.scratch.refinenet3(path_4, layer_3_rn, size=layer_2_rn.shape[2:])
|
||||
path_2 = self.scratch.refinenet2(path_3, layer_2_rn, size=layer_1_rn.shape[2:])
|
||||
path_1 = self.scratch.refinenet1(path_2, layer_1_rn)
|
||||
|
||||
if self.scratch.stem_transpose is not None:
|
||||
path_1 = self.scratch.stem_transpose(path_1)
|
||||
|
||||
out = self.scratch.output_conv(path_1)
|
||||
|
||||
return out
|
||||
|
||||
|
||||
class DPTDepthModel(DPT):
|
||||
def __init__(self, path=None, non_negative=True, **kwargs):
|
||||
features = kwargs["features"] if "features" in kwargs else 256
|
||||
head_features_1 = kwargs["head_features_1"] if "head_features_1" in kwargs else features
|
||||
head_features_2 = kwargs["head_features_2"] if "head_features_2" in kwargs else 32
|
||||
kwargs.pop("head_features_1", None)
|
||||
kwargs.pop("head_features_2", None)
|
||||
|
||||
head = nn.Sequential(
|
||||
nn.Conv2d(head_features_1, head_features_1 // 2, kernel_size=3, stride=1, padding=1),
|
||||
Interpolate(scale_factor=2, mode="bilinear", align_corners=True),
|
||||
nn.Conv2d(head_features_1 // 2, head_features_2, kernel_size=3, stride=1, padding=1),
|
||||
nn.ReLU(True),
|
||||
nn.Conv2d(head_features_2, 1, kernel_size=1, stride=1, padding=0),
|
||||
nn.ReLU(True) if non_negative else nn.Identity(),
|
||||
nn.Identity(),
|
||||
)
|
||||
|
||||
super().__init__(head, **kwargs)
|
||||
|
||||
if path is not None:
|
||||
self.load(path)
|
||||
|
||||
def forward(self, x):
|
||||
return super().forward(x).squeeze(dim=1)
|
||||
@@ -0,0 +1,76 @@
|
||||
"""MidashNet: Network for monocular depth estimation trained by mixing several datasets.
|
||||
This file contains code that is adapted from
|
||||
https://github.com/thomasjpfan/pytorch_refinenet/blob/master/pytorch_refinenet/refinenet/refinenet_4cascade.py
|
||||
"""
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
|
||||
from .base_model import BaseModel
|
||||
from .blocks import FeatureFusionBlock, Interpolate, _make_encoder
|
||||
|
||||
|
||||
class MidasNet(BaseModel):
|
||||
"""Network for monocular depth estimation.
|
||||
"""
|
||||
|
||||
def __init__(self, path=None, features=256, non_negative=True):
|
||||
"""Init.
|
||||
|
||||
Args:
|
||||
path (str, optional): Path to saved model. Defaults to None.
|
||||
features (int, optional): Number of features. Defaults to 256.
|
||||
backbone (str, optional): Backbone network for encoder. Defaults to resnet50
|
||||
"""
|
||||
print("Loading weights: ", path)
|
||||
|
||||
super(MidasNet, self).__init__()
|
||||
|
||||
use_pretrained = False if path is None else True
|
||||
|
||||
self.pretrained, self.scratch = _make_encoder(backbone="resnext101_wsl", features=features, use_pretrained=use_pretrained)
|
||||
|
||||
self.scratch.refinenet4 = FeatureFusionBlock(features)
|
||||
self.scratch.refinenet3 = FeatureFusionBlock(features)
|
||||
self.scratch.refinenet2 = FeatureFusionBlock(features)
|
||||
self.scratch.refinenet1 = FeatureFusionBlock(features)
|
||||
|
||||
self.scratch.output_conv = nn.Sequential(
|
||||
nn.Conv2d(features, 128, kernel_size=3, stride=1, padding=1),
|
||||
Interpolate(scale_factor=2, mode="bilinear"),
|
||||
nn.Conv2d(128, 32, kernel_size=3, stride=1, padding=1),
|
||||
nn.ReLU(True),
|
||||
nn.Conv2d(32, 1, kernel_size=1, stride=1, padding=0),
|
||||
nn.ReLU(True) if non_negative else nn.Identity(),
|
||||
)
|
||||
|
||||
if path:
|
||||
self.load(path)
|
||||
|
||||
def forward(self, x):
|
||||
"""Forward pass.
|
||||
|
||||
Args:
|
||||
x (tensor): input data (image)
|
||||
|
||||
Returns:
|
||||
tensor: depth
|
||||
"""
|
||||
|
||||
layer_1 = self.pretrained.layer1(x)
|
||||
layer_2 = self.pretrained.layer2(layer_1)
|
||||
layer_3 = self.pretrained.layer3(layer_2)
|
||||
layer_4 = self.pretrained.layer4(layer_3)
|
||||
|
||||
layer_1_rn = self.scratch.layer1_rn(layer_1)
|
||||
layer_2_rn = self.scratch.layer2_rn(layer_2)
|
||||
layer_3_rn = self.scratch.layer3_rn(layer_3)
|
||||
layer_4_rn = self.scratch.layer4_rn(layer_4)
|
||||
|
||||
path_4 = self.scratch.refinenet4(layer_4_rn)
|
||||
path_3 = self.scratch.refinenet3(path_4, layer_3_rn)
|
||||
path_2 = self.scratch.refinenet2(path_3, layer_2_rn)
|
||||
path_1 = self.scratch.refinenet1(path_2, layer_1_rn)
|
||||
|
||||
out = self.scratch.output_conv(path_1)
|
||||
|
||||
return torch.squeeze(out, dim=1)
|
||||
@@ -0,0 +1,129 @@
|
||||
"""MidashNet: Network for monocular depth estimation trained by mixing several datasets.
|
||||
This file contains code that is adapted from
|
||||
https://github.com/thomasjpfan/pytorch_refinenet/blob/master/pytorch_refinenet/refinenet/refinenet_4cascade.py
|
||||
"""
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
|
||||
from .base_model import BaseModel
|
||||
from .blocks import (FeatureFusionBlock, FeatureFusionBlock_custom,
|
||||
Interpolate, _make_encoder)
|
||||
|
||||
|
||||
class MidasNet_small(BaseModel):
|
||||
"""Network for monocular depth estimation.
|
||||
"""
|
||||
|
||||
def __init__(self, path=None, features=64, backbone="efficientnet_lite3", non_negative=True, exportable=True, channels_last=False, align_corners=True,
|
||||
blocks={'expand': True}):
|
||||
"""Init.
|
||||
|
||||
Args:
|
||||
path (str, optional): Path to saved model. Defaults to None.
|
||||
features (int, optional): Number of features. Defaults to 256.
|
||||
backbone (str, optional): Backbone network for encoder. Defaults to resnet50
|
||||
"""
|
||||
print("Loading weights: ", path)
|
||||
|
||||
super(MidasNet_small, self).__init__()
|
||||
|
||||
use_pretrained = False if path else True
|
||||
|
||||
self.channels_last = channels_last
|
||||
self.blocks = blocks
|
||||
self.backbone = backbone
|
||||
|
||||
self.groups = 1
|
||||
|
||||
features1=features
|
||||
features2=features
|
||||
features3=features
|
||||
features4=features
|
||||
self.expand = False
|
||||
if "expand" in self.blocks and self.blocks['expand'] == True:
|
||||
self.expand = True
|
||||
features1=features
|
||||
features2=features*2
|
||||
features3=features*4
|
||||
features4=features*8
|
||||
|
||||
self.pretrained, self.scratch = _make_encoder(self.backbone, features, use_pretrained, groups=self.groups, expand=self.expand, exportable=exportable)
|
||||
|
||||
self.scratch.activation = nn.ReLU(False)
|
||||
|
||||
self.scratch.refinenet4 = FeatureFusionBlock_custom(features4, self.scratch.activation, deconv=False, bn=False, expand=self.expand, align_corners=align_corners)
|
||||
self.scratch.refinenet3 = FeatureFusionBlock_custom(features3, self.scratch.activation, deconv=False, bn=False, expand=self.expand, align_corners=align_corners)
|
||||
self.scratch.refinenet2 = FeatureFusionBlock_custom(features2, self.scratch.activation, deconv=False, bn=False, expand=self.expand, align_corners=align_corners)
|
||||
self.scratch.refinenet1 = FeatureFusionBlock_custom(features1, self.scratch.activation, deconv=False, bn=False, align_corners=align_corners)
|
||||
|
||||
|
||||
self.scratch.output_conv = nn.Sequential(
|
||||
nn.Conv2d(features, features//2, kernel_size=3, stride=1, padding=1, groups=self.groups),
|
||||
Interpolate(scale_factor=2, mode="bilinear"),
|
||||
nn.Conv2d(features//2, 32, kernel_size=3, stride=1, padding=1),
|
||||
self.scratch.activation,
|
||||
nn.Conv2d(32, 1, kernel_size=1, stride=1, padding=0),
|
||||
nn.ReLU(True) if non_negative else nn.Identity(),
|
||||
nn.Identity(),
|
||||
)
|
||||
|
||||
if path:
|
||||
self.load(path)
|
||||
|
||||
|
||||
def forward(self, x):
|
||||
"""Forward pass.
|
||||
|
||||
Args:
|
||||
x (tensor): input data (image)
|
||||
|
||||
Returns:
|
||||
tensor: depth
|
||||
"""
|
||||
if self.channels_last==True:
|
||||
print("self.channels_last = ", self.channels_last)
|
||||
x.contiguous(memory_format=torch.channels_last)
|
||||
|
||||
|
||||
layer_1 = self.pretrained.layer1(x)
|
||||
layer_2 = self.pretrained.layer2(layer_1)
|
||||
layer_3 = self.pretrained.layer3(layer_2)
|
||||
layer_4 = self.pretrained.layer4(layer_3)
|
||||
|
||||
layer_1_rn = self.scratch.layer1_rn(layer_1)
|
||||
layer_2_rn = self.scratch.layer2_rn(layer_2)
|
||||
layer_3_rn = self.scratch.layer3_rn(layer_3)
|
||||
layer_4_rn = self.scratch.layer4_rn(layer_4)
|
||||
|
||||
|
||||
path_4 = self.scratch.refinenet4(layer_4_rn)
|
||||
path_3 = self.scratch.refinenet3(path_4, layer_3_rn)
|
||||
path_2 = self.scratch.refinenet2(path_3, layer_2_rn)
|
||||
path_1 = self.scratch.refinenet1(path_2, layer_1_rn)
|
||||
|
||||
out = self.scratch.output_conv(path_1)
|
||||
|
||||
return torch.squeeze(out, dim=1)
|
||||
|
||||
|
||||
|
||||
def fuse_model(m):
|
||||
prev_previous_type = nn.Identity()
|
||||
prev_previous_name = ''
|
||||
previous_type = nn.Identity()
|
||||
previous_name = ''
|
||||
for name, module in m.named_modules():
|
||||
if prev_previous_type == nn.Conv2d and previous_type == nn.BatchNorm2d and type(module) == nn.ReLU:
|
||||
# print("FUSED ", prev_previous_name, previous_name, name)
|
||||
torch.quantization.fuse_modules(m, [prev_previous_name, previous_name, name], inplace=True)
|
||||
elif prev_previous_type == nn.Conv2d and previous_type == nn.BatchNorm2d:
|
||||
# print("FUSED ", prev_previous_name, previous_name)
|
||||
torch.quantization.fuse_modules(m, [prev_previous_name, previous_name], inplace=True)
|
||||
# elif previous_type == nn.Conv2d and type(module) == nn.ReLU:
|
||||
# print("FUSED ", previous_name, name)
|
||||
# torch.quantization.fuse_modules(m, [previous_name, name], inplace=True)
|
||||
|
||||
prev_previous_type = previous_type
|
||||
prev_previous_name = previous_name
|
||||
previous_type = type(module)
|
||||
previous_name = name
|
||||
@@ -0,0 +1,240 @@
|
||||
import cv2
|
||||
import torch
|
||||
from midas.dpt_depth import DPTDepthModel
|
||||
from midas.midas_net import MidasNet
|
||||
from midas.midas_net_custom import MidasNet_small
|
||||
from midas.transforms import NormalizeImage, PrepareForNet, Resize
|
||||
from torchvision.transforms import Compose
|
||||
|
||||
default_models = {
|
||||
"dpt_beit_large_512": "weights/dpt_beit_large_512.pt",
|
||||
"dpt_beit_large_384": "weights/dpt_beit_large_384.pt",
|
||||
"dpt_beit_base_384": "weights/dpt_beit_base_384.pt",
|
||||
"dpt_swin2_large_384": "weights/dpt_swin2_large_384.pt",
|
||||
"dpt_swin2_base_384": "weights/dpt_swin2_base_384.pt",
|
||||
"dpt_swin2_tiny_256": "weights/dpt_swin2_tiny_256.pt",
|
||||
"dpt_swin_large_384": "weights/dpt_swin_large_384.pt",
|
||||
"dpt_next_vit_large_384": "weights/dpt_next_vit_large_384.pt",
|
||||
"dpt_levit_224": "weights/dpt_levit_224.pt",
|
||||
"dpt_large_384": "weights/dpt_large_384.pt",
|
||||
"dpt_hybrid_384": "weights/dpt_hybrid_384.pt",
|
||||
"midas_v21_384": "weights/midas_v21_384.pt",
|
||||
"midas_v21_small_256": "weights/midas_v21_small_256.pt",
|
||||
"openvino_midas_v21_small_256": "weights/openvino_midas_v21_small_256.xml",
|
||||
}
|
||||
|
||||
|
||||
def load_model(device, model_path, model_type="dpt_large_384", optimize=True, height=None, square=False):
|
||||
"""Load the specified network.
|
||||
|
||||
Args:
|
||||
device (device): the torch device used
|
||||
model_path (str): path to saved model
|
||||
model_type (str): the type of the model to be loaded
|
||||
optimize (bool): optimize the model to half-integer on CUDA?
|
||||
height (int): inference encoder image height
|
||||
square (bool): resize to a square resolution?
|
||||
|
||||
Returns:
|
||||
The loaded network, the transform which prepares images as input to the network and the dimensions of the
|
||||
network input
|
||||
"""
|
||||
if "openvino" in model_type:
|
||||
from openvino.runtime import Core
|
||||
|
||||
keep_aspect_ratio = not square
|
||||
|
||||
if model_type == "dpt_beit_large_512":
|
||||
model = DPTDepthModel(
|
||||
path=model_path,
|
||||
backbone="beitl16_512",
|
||||
non_negative=True,
|
||||
)
|
||||
net_w, net_h = 512, 512
|
||||
resize_mode = "minimal"
|
||||
normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
|
||||
|
||||
elif model_type == "dpt_beit_large_384":
|
||||
model = DPTDepthModel(
|
||||
path=model_path,
|
||||
backbone="beitl16_384",
|
||||
non_negative=True,
|
||||
)
|
||||
net_w, net_h = 384, 384
|
||||
resize_mode = "minimal"
|
||||
normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
|
||||
|
||||
elif model_type == "dpt_beit_base_384":
|
||||
model = DPTDepthModel(
|
||||
path=model_path,
|
||||
backbone="beitb16_384",
|
||||
non_negative=True,
|
||||
)
|
||||
net_w, net_h = 384, 384
|
||||
resize_mode = "minimal"
|
||||
normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
|
||||
|
||||
elif model_type == "dpt_swin2_large_384":
|
||||
model = DPTDepthModel(
|
||||
path=model_path,
|
||||
backbone="swin2l24_384",
|
||||
non_negative=True,
|
||||
)
|
||||
net_w, net_h = 384, 384
|
||||
keep_aspect_ratio = False
|
||||
resize_mode = "minimal"
|
||||
normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
|
||||
|
||||
elif model_type == "dpt_swin2_base_384":
|
||||
model = DPTDepthModel(
|
||||
path=model_path,
|
||||
backbone="swin2b24_384",
|
||||
non_negative=True,
|
||||
)
|
||||
net_w, net_h = 384, 384
|
||||
keep_aspect_ratio = False
|
||||
resize_mode = "minimal"
|
||||
normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
|
||||
|
||||
elif model_type == "dpt_swin2_tiny_256":
|
||||
model = DPTDepthModel(
|
||||
path=model_path,
|
||||
backbone="swin2t16_256",
|
||||
non_negative=True,
|
||||
)
|
||||
net_w, net_h = 256, 256
|
||||
keep_aspect_ratio = False
|
||||
resize_mode = "minimal"
|
||||
normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
|
||||
|
||||
elif model_type == "dpt_swin_large_384":
|
||||
model = DPTDepthModel(
|
||||
path=model_path,
|
||||
backbone="swinl12_384",
|
||||
non_negative=True,
|
||||
)
|
||||
net_w, net_h = 384, 384
|
||||
keep_aspect_ratio = False
|
||||
resize_mode = "minimal"
|
||||
normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
|
||||
|
||||
elif model_type == "dpt_next_vit_large_384":
|
||||
model = DPTDepthModel(
|
||||
path=model_path,
|
||||
backbone="next_vit_large_6m",
|
||||
non_negative=True,
|
||||
)
|
||||
net_w, net_h = 384, 384
|
||||
resize_mode = "minimal"
|
||||
normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
|
||||
|
||||
# We change the notation from dpt_levit_224 (MiDaS notation) to levit_384 (timm notation) here, where the 224 refers
|
||||
# to the resolution 224x224 used by LeViT and 384 is the first entry of the embed_dim, see _cfg and model_cfgs of
|
||||
# https://github.com/rwightman/pytorch-image-models/blob/main/timm/models/levit.py
|
||||
# (commit id: 927f031293a30afb940fff0bee34b85d9c059b0e)
|
||||
elif model_type == "dpt_levit_224":
|
||||
model = DPTDepthModel(
|
||||
path=model_path,
|
||||
backbone="levit_384",
|
||||
non_negative=True,
|
||||
head_features_1=64,
|
||||
head_features_2=8,
|
||||
)
|
||||
net_w, net_h = 224, 224
|
||||
keep_aspect_ratio = False
|
||||
resize_mode = "minimal"
|
||||
normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
|
||||
|
||||
elif model_type == "dpt_large_384":
|
||||
model = DPTDepthModel(
|
||||
path=model_path,
|
||||
backbone="vitl16_384",
|
||||
non_negative=True,
|
||||
)
|
||||
net_w, net_h = 384, 384
|
||||
resize_mode = "minimal"
|
||||
normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
|
||||
|
||||
elif model_type == "dpt_hybrid_384":
|
||||
model = DPTDepthModel(
|
||||
path=model_path,
|
||||
backbone="vitb_rn50_384",
|
||||
non_negative=True,
|
||||
)
|
||||
net_w, net_h = 384, 384
|
||||
resize_mode = "minimal"
|
||||
normalization = NormalizeImage(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5])
|
||||
|
||||
elif model_type == "midas_v21_384":
|
||||
model = MidasNet(model_path, non_negative=True)
|
||||
net_w, net_h = 384, 384
|
||||
resize_mode = "upper_bound"
|
||||
normalization = NormalizeImage(
|
||||
mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225]
|
||||
)
|
||||
|
||||
elif model_type == "midas_v21_small_256":
|
||||
model = MidasNet_small(model_path, features=64, backbone="efficientnet_lite3", exportable=True,
|
||||
non_negative=True, blocks={'expand': True})
|
||||
net_w, net_h = 256, 256
|
||||
resize_mode = "upper_bound"
|
||||
normalization = NormalizeImage(
|
||||
mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225]
|
||||
)
|
||||
|
||||
elif model_type == "openvino_midas_v21_small_256":
|
||||
ie = Core()
|
||||
uncompiled_model = ie.read_model(model=model_path)
|
||||
model = ie.compile_model(uncompiled_model, "CPU")
|
||||
net_w, net_h = 256, 256
|
||||
resize_mode = "upper_bound"
|
||||
normalization = NormalizeImage(
|
||||
mean=[0.485, 0.456, 0.406], std=[0.229, 0.224, 0.225]
|
||||
)
|
||||
|
||||
else:
|
||||
print(f"model_type '{model_type}' not implemented, use: --model_type large")
|
||||
assert False
|
||||
|
||||
if not "openvino" in model_type:
|
||||
print("Model loaded, number of parameters = {:.0f}M".format(sum(p.numel() for p in model.parameters()) / 1e6))
|
||||
else:
|
||||
print("Model loaded, optimized with OpenVINO")
|
||||
|
||||
if "openvino" in model_type:
|
||||
keep_aspect_ratio = False
|
||||
|
||||
if height is not None:
|
||||
net_w, net_h = height, height
|
||||
|
||||
transform = Compose(
|
||||
[
|
||||
Resize(
|
||||
net_w,
|
||||
net_h,
|
||||
resize_target=None,
|
||||
keep_aspect_ratio=keep_aspect_ratio,
|
||||
ensure_multiple_of=32,
|
||||
resize_method=resize_mode,
|
||||
image_interpolation_method=cv2.INTER_CUBIC,
|
||||
),
|
||||
normalization,
|
||||
PrepareForNet(),
|
||||
]
|
||||
)
|
||||
|
||||
if not "openvino" in model_type:
|
||||
model.eval()
|
||||
|
||||
if optimize and (device == torch.device("cuda")):
|
||||
if not "openvino" in model_type:
|
||||
model = model.to(memory_format=torch.channels_last)
|
||||
model = model.half()
|
||||
else:
|
||||
print("Error: OpenVINO models are already optimized. No optimization to half-float possible.")
|
||||
exit()
|
||||
|
||||
if not "openvino" in model_type:
|
||||
model.to(device)
|
||||
|
||||
return model, transform, net_w, net_h
|
||||
@@ -0,0 +1,235 @@
|
||||
import math
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
|
||||
|
||||
def apply_min_size(sample, size, image_interpolation_method=cv2.INTER_AREA):
|
||||
"""Rezise the sample to ensure the given size. Keeps aspect ratio.
|
||||
|
||||
Args:
|
||||
sample (dict): sample
|
||||
size (tuple): image size
|
||||
|
||||
Returns:
|
||||
tuple: new size
|
||||
"""
|
||||
shape = list(sample["disparity"].shape)
|
||||
|
||||
if shape[0] >= size[0] and shape[1] >= size[1]:
|
||||
return sample
|
||||
|
||||
scale = [0, 0]
|
||||
scale[0] = size[0] / shape[0]
|
||||
scale[1] = size[1] / shape[1]
|
||||
|
||||
scale = max(scale)
|
||||
|
||||
shape[0] = math.ceil(scale * shape[0])
|
||||
shape[1] = math.ceil(scale * shape[1])
|
||||
|
||||
# resize
|
||||
sample["image"] = cv2.resize(
|
||||
sample["image"], tuple(shape[::-1]), interpolation=image_interpolation_method
|
||||
)
|
||||
|
||||
sample["disparity"] = cv2.resize(
|
||||
sample["disparity"], tuple(shape[::-1]), interpolation=cv2.INTER_NEAREST
|
||||
)
|
||||
sample["mask"] = cv2.resize(
|
||||
sample["mask"].astype(np.float32),
|
||||
tuple(shape[::-1]),
|
||||
interpolation=cv2.INTER_NEAREST,
|
||||
)
|
||||
sample["mask"] = sample["mask"].astype(bool)
|
||||
|
||||
return tuple(shape)
|
||||
|
||||
|
||||
class Resize(object):
|
||||
"""Resize sample to given size (width, height).
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
width,
|
||||
height,
|
||||
resize_target=True,
|
||||
keep_aspect_ratio=False,
|
||||
ensure_multiple_of=1,
|
||||
resize_method="lower_bound",
|
||||
image_interpolation_method=cv2.INTER_AREA,
|
||||
):
|
||||
"""Init.
|
||||
|
||||
Args:
|
||||
width (int): desired output width
|
||||
height (int): desired output height
|
||||
resize_target (bool, optional):
|
||||
True: Resize the full sample (image, mask, target).
|
||||
False: Resize image only.
|
||||
Defaults to True.
|
||||
keep_aspect_ratio (bool, optional):
|
||||
True: Keep the aspect ratio of the input sample.
|
||||
Output sample might not have the given width and height, and
|
||||
resize behaviour depends on the parameter 'resize_method'.
|
||||
Defaults to False.
|
||||
ensure_multiple_of (int, optional):
|
||||
Output width and height is constrained to be multiple of this parameter.
|
||||
Defaults to 1.
|
||||
resize_method (str, optional):
|
||||
"lower_bound": Output will be at least as large as the given size.
|
||||
"upper_bound": Output will be at max as large as the given size. (Output size might be smaller than given size.)
|
||||
"minimal": Scale as least as possible. (Output size might be smaller than given size.)
|
||||
Defaults to "lower_bound".
|
||||
"""
|
||||
self.__width = width
|
||||
self.__height = height
|
||||
|
||||
self.__resize_target = resize_target
|
||||
self.__keep_aspect_ratio = keep_aspect_ratio
|
||||
self.__multiple_of = ensure_multiple_of
|
||||
self.__resize_method = resize_method
|
||||
self.__image_interpolation_method = image_interpolation_method
|
||||
|
||||
def constrain_to_multiple_of(self, x, min_val=0, max_val=None):
|
||||
y = (np.round(x / self.__multiple_of) * self.__multiple_of).astype(int)
|
||||
|
||||
if max_val is not None and y > max_val:
|
||||
y = (np.floor(x / self.__multiple_of) * self.__multiple_of).astype(int)
|
||||
|
||||
if y < min_val:
|
||||
y = (np.ceil(x / self.__multiple_of) * self.__multiple_of).astype(int)
|
||||
|
||||
return y
|
||||
|
||||
def get_size(self, width, height):
|
||||
# determine new height and width
|
||||
scale_height = self.__height / height
|
||||
scale_width = self.__width / width
|
||||
|
||||
if self.__keep_aspect_ratio:
|
||||
if self.__resize_method == "lower_bound":
|
||||
# scale such that output size is lower bound
|
||||
if scale_width > scale_height:
|
||||
# fit width
|
||||
scale_height = scale_width
|
||||
else:
|
||||
# fit height
|
||||
scale_width = scale_height
|
||||
elif self.__resize_method == "upper_bound":
|
||||
# scale such that output size is upper bound
|
||||
if scale_width < scale_height:
|
||||
# fit width
|
||||
scale_height = scale_width
|
||||
else:
|
||||
# fit height
|
||||
scale_width = scale_height
|
||||
elif self.__resize_method == "minimal":
|
||||
# scale as least as possbile
|
||||
if abs(1 - scale_width) < abs(1 - scale_height):
|
||||
# fit width
|
||||
scale_height = scale_width
|
||||
else:
|
||||
# fit height
|
||||
scale_width = scale_height
|
||||
else:
|
||||
raise ValueError(
|
||||
f"resize_method {self.__resize_method} not implemented"
|
||||
)
|
||||
|
||||
if self.__resize_method == "lower_bound":
|
||||
new_height = self.constrain_to_multiple_of(
|
||||
scale_height * height, min_val=self.__height
|
||||
)
|
||||
new_width = self.constrain_to_multiple_of(
|
||||
scale_width * width, min_val=self.__width
|
||||
)
|
||||
elif self.__resize_method == "upper_bound":
|
||||
new_height = self.constrain_to_multiple_of(
|
||||
scale_height * height, max_val=self.__height
|
||||
)
|
||||
new_width = self.constrain_to_multiple_of(
|
||||
scale_width * width, max_val=self.__width
|
||||
)
|
||||
elif self.__resize_method == "minimal":
|
||||
new_height = self.constrain_to_multiple_of(scale_height * height)
|
||||
new_width = self.constrain_to_multiple_of(scale_width * width)
|
||||
else:
|
||||
raise ValueError(f"resize_method {self.__resize_method} not implemented")
|
||||
|
||||
return (new_width, new_height)
|
||||
|
||||
def __call__(self, sample):
|
||||
width, height = self.get_size(
|
||||
sample["image"].shape[1], sample["image"].shape[0]
|
||||
)
|
||||
|
||||
# resize sample
|
||||
sample["image"] = cv2.resize(
|
||||
sample["image"],
|
||||
(width, height),
|
||||
interpolation=self.__image_interpolation_method,
|
||||
)
|
||||
|
||||
if self.__resize_target:
|
||||
if "disparity" in sample:
|
||||
sample["disparity"] = cv2.resize(
|
||||
sample["disparity"],
|
||||
(width, height),
|
||||
interpolation=cv2.INTER_NEAREST,
|
||||
)
|
||||
|
||||
if "depth" in sample:
|
||||
sample["depth"] = cv2.resize(
|
||||
sample["depth"], (width, height), interpolation=cv2.INTER_NEAREST
|
||||
)
|
||||
|
||||
sample["mask"] = cv2.resize(
|
||||
sample["mask"].astype(np.float32),
|
||||
(width, height),
|
||||
interpolation=cv2.INTER_NEAREST,
|
||||
)
|
||||
sample["mask"] = sample["mask"].astype(bool)
|
||||
|
||||
return sample
|
||||
|
||||
|
||||
class NormalizeImage(object):
|
||||
"""Normlize image by given mean and std.
|
||||
"""
|
||||
|
||||
def __init__(self, mean, std):
|
||||
self.__mean = mean
|
||||
self.__std = std
|
||||
|
||||
def __call__(self, sample):
|
||||
sample["image"] = (sample["image"] - self.__mean) / self.__std
|
||||
|
||||
return sample
|
||||
|
||||
|
||||
class PrepareForNet(object):
|
||||
"""Prepare sample for usage as network input.
|
||||
"""
|
||||
|
||||
def __init__(self):
|
||||
pass
|
||||
|
||||
def __call__(self, sample):
|
||||
image = np.transpose(sample["image"], (2, 0, 1))
|
||||
sample["image"] = np.ascontiguousarray(image).astype(np.float32)
|
||||
|
||||
if "mask" in sample:
|
||||
sample["mask"] = sample["mask"].astype(np.float32)
|
||||
sample["mask"] = np.ascontiguousarray(sample["mask"])
|
||||
|
||||
if "disparity" in sample:
|
||||
disparity = sample["disparity"].astype(np.float32)
|
||||
sample["disparity"] = np.ascontiguousarray(disparity)
|
||||
|
||||
if "depth" in sample:
|
||||
depth = sample["depth"].astype(np.float32)
|
||||
sample["depth"] = np.ascontiguousarray(depth)
|
||||
|
||||
return sample
|
||||
@@ -0,0 +1,21 @@
|
||||
MIT License
|
||||
|
||||
Copyright (c) 2020 Alexey
|
||||
|
||||
Permission is hereby granted, free of charge, to any person obtaining a copy
|
||||
of this software and associated documentation files (the "Software"), to deal
|
||||
in the Software without restriction, including without limitation the rights
|
||||
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
||||
copies of the Software, and to permit persons to whom the Software is
|
||||
furnished to do so, subject to the following conditions:
|
||||
|
||||
The above copyright notice and this permission notice shall be included in all
|
||||
copies or substantial portions of the Software.
|
||||
|
||||
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
||||
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
||||
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
||||
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
||||
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
||||
OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE
|
||||
SOFTWARE.
|
||||
@@ -0,0 +1,131 @@
|
||||
# MiDaS for ROS1 by using LibTorch in C++
|
||||
|
||||
### Requirements
|
||||
|
||||
- Ubuntu 17.10 / 18.04 / 20.04, Debian Stretch
|
||||
- ROS Melodic for Ubuntu (17.10 / 18.04) / Debian Stretch, ROS Noetic for Ubuntu 20.04
|
||||
- C++11
|
||||
- LibTorch >= 1.6
|
||||
|
||||
## Quick Start with a MiDaS Example
|
||||
|
||||
MiDaS is a neural network to compute depth from a single image.
|
||||
|
||||
* input from `image_topic`: `sensor_msgs/Image` - `RGB8` image with any shape
|
||||
* output to `midas_topic`: `sensor_msgs/Image` - `TYPE_32FC1` inverse relative depth maps in range [0 - 255] with original size and channels=1
|
||||
|
||||
### Install Dependecies
|
||||
|
||||
* install ROS Melodic for Ubuntu 17.10 / 18.04:
|
||||
```bash
|
||||
wget https://raw.githubusercontent.com/isl-org/MiDaS/master/ros/additions/install_ros_melodic_ubuntu_17_18.sh
|
||||
./install_ros_melodic_ubuntu_17_18.sh
|
||||
```
|
||||
|
||||
or Noetic for Ubuntu 20.04:
|
||||
|
||||
```bash
|
||||
wget https://raw.githubusercontent.com/isl-org/MiDaS/master/ros/additions/install_ros_noetic_ubuntu_20.sh
|
||||
./install_ros_noetic_ubuntu_20.sh
|
||||
```
|
||||
|
||||
|
||||
* install LibTorch 1.7 with CUDA 11.0:
|
||||
|
||||
On **Jetson (ARM)**:
|
||||
```bash
|
||||
wget https://nvidia.box.com/shared/static/wa34qwrwtk9njtyarwt5nvo6imenfy26.whl -O torch-1.7.0-cp36-cp36m-linux_aarch64.whl
|
||||
sudo apt-get install python3-pip libopenblas-base libopenmpi-dev
|
||||
pip3 install Cython
|
||||
pip3 install numpy torch-1.7.0-cp36-cp36m-linux_aarch64.whl
|
||||
```
|
||||
Or compile LibTorch from source: https://github.com/pytorch/pytorch#from-source
|
||||
|
||||
On **Linux (x86_64)**:
|
||||
```bash
|
||||
cd ~/
|
||||
wget https://download.pytorch.org/libtorch/cu110/libtorch-cxx11-abi-shared-with-deps-1.7.0%2Bcu110.zip
|
||||
unzip libtorch-cxx11-abi-shared-with-deps-1.7.0+cu110.zip
|
||||
```
|
||||
|
||||
* create symlink for OpenCV:
|
||||
|
||||
```bash
|
||||
sudo ln -s /usr/include/opencv4 /usr/include/opencv
|
||||
```
|
||||
|
||||
* download and install MiDaS:
|
||||
|
||||
```bash
|
||||
source ~/.bashrc
|
||||
cd ~/
|
||||
mkdir catkin_ws
|
||||
cd catkin_ws
|
||||
git clone https://github.com/isl-org/MiDaS
|
||||
mkdir src
|
||||
cp -r MiDaS/ros/* src
|
||||
|
||||
chmod +x src/additions/*.sh
|
||||
chmod +x src/*.sh
|
||||
chmod +x src/midas_cpp/scripts/*.py
|
||||
cp src/additions/do_catkin_make.sh ./do_catkin_make.sh
|
||||
./do_catkin_make.sh
|
||||
./src/additions/downloads.sh
|
||||
```
|
||||
|
||||
### Usage
|
||||
|
||||
* run only `midas` node: `~/catkin_ws/src/launch_midas_cpp.sh`
|
||||
|
||||
#### Test
|
||||
|
||||
* Test - capture video and show result in the window:
|
||||
* place any `test.mp4` video file to the directory `~/catkin_ws/src/`
|
||||
* run `midas` node: `~/catkin_ws/src/launch_midas_cpp.sh`
|
||||
* run test nodes in another terminal: `cd ~/catkin_ws/src && ./run_talker_listener_test.sh` and wait 30 seconds
|
||||
|
||||
(to use Python 2, run command `sed -i 's/python3/python2/' ~/catkin_ws/src/midas_cpp/scripts/*.py` )
|
||||
|
||||
## Mobile version of MiDaS - Monocular Depth Estimation
|
||||
|
||||
### Accuracy
|
||||
|
||||
* MiDaS v2 small - ResNet50 default-decoder 384x384
|
||||
* MiDaS v2.1 small - EfficientNet-Lite3 small-decoder 256x256
|
||||
|
||||
**Zero-shot error** (the lower - the better):
|
||||
|
||||
| Model | DIW WHDR | Eth3d AbsRel | Sintel AbsRel | Kitti δ>1.25 | NyuDepthV2 δ>1.25 | TUM δ>1.25 |
|
||||
|---|---|---|---|---|---|---|
|
||||
| MiDaS v2 small 384x384 | **0.1248** | 0.1550 | **0.3300** | **21.81** | 15.73 | 17.00 |
|
||||
| MiDaS v2.1 small 256x256 | 0.1344 | **0.1344** | 0.3370 | 29.27 | **13.43** | **14.53** |
|
||||
| Relative improvement, % | -8 % | **+13 %** | -2 % | -34 % | **+15 %** | **+15 %** |
|
||||
|
||||
None of Train/Valid/Test subsets of datasets (DIW, Eth3d, Sintel, Kitti, NyuDepthV2, TUM) were not involved in Training or Fine Tuning.
|
||||
|
||||
### Inference speed (FPS) on nVidia GPU
|
||||
|
||||
Inference speed excluding pre and post processing, batch=1, **Frames Per Second** (the higher - the better):
|
||||
|
||||
| Model | Jetson Nano, FPS | RTX 2080Ti, FPS |
|
||||
|---|---|---|
|
||||
| MiDaS v2 small 384x384 | 1.6 | 117 |
|
||||
| MiDaS v2.1 small 256x256 | 8.1 | 232 |
|
||||
| SpeedUp, X times | **5x** | **2x** |
|
||||
|
||||
### Citation
|
||||
|
||||
This repository contains code to compute depth from a single image. It accompanies our [paper](https://arxiv.org/abs/1907.01341v3):
|
||||
|
||||
>Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-shot Cross-dataset Transfer
|
||||
René Ranftl, Katrin Lasinger, David Hafner, Konrad Schindler, Vladlen Koltun
|
||||
|
||||
Please cite our paper if you use this code or any of the models:
|
||||
```
|
||||
@article{Ranftl2020,
|
||||
author = {Ren\'{e} Ranftl and Katrin Lasinger and David Hafner and Konrad Schindler and Vladlen Koltun},
|
||||
title = {Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-shot Cross-dataset Transfer},
|
||||
journal = {IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI)},
|
||||
year = {2020},
|
||||
}
|
||||
```
|
||||
@@ -0,0 +1,5 @@
|
||||
mkdir src
|
||||
catkin_make
|
||||
source devel/setup.bash
|
||||
echo $ROS_PACKAGE_PATH
|
||||
chmod +x ./devel/setup.bash
|
||||
@@ -0,0 +1,5 @@
|
||||
mkdir ~/.ros
|
||||
wget https://github.com/isl-org/MiDaS/releases/download/v2_1/model-small-traced.pt
|
||||
cp ./model-small-traced.pt ~/.ros/model-small-traced.pt
|
||||
|
||||
|
||||
@@ -0,0 +1,34 @@
|
||||
#@title { display-mode: "code" }
|
||||
|
||||
#from http://wiki.ros.org/indigo/Installation/Ubuntu
|
||||
|
||||
#1.2 Setup sources.list
|
||||
sudo sh -c 'echo "deb http://packages.ros.org/ros/ubuntu $(lsb_release -sc) main" > /etc/apt/sources.list.d/ros-latest.list'
|
||||
|
||||
# 1.3 Setup keys
|
||||
sudo apt-key adv --keyserver 'hkp://keyserver.ubuntu.com:80' --recv-key C1CF6E31E6BADE8868B172B4F42ED6FBAB17C654
|
||||
sudo apt-key adv --keyserver 'hkp://ha.pool.sks-keyservers.net:80' --recv-key 421C365BD9FF1F717815A3895523BAEEB01FA116
|
||||
|
||||
curl -sSL 'http://keyserver.ubuntu.com/pks/lookup?op=get&search=0xC1CF6E31E6BADE8868B172B4F42ED6FBAB17C654' | sudo apt-key add -
|
||||
|
||||
# 1.4 Installation
|
||||
sudo apt-get update
|
||||
sudo apt-get upgrade
|
||||
|
||||
# Desktop-Full Install:
|
||||
sudo apt-get install ros-melodic-desktop-full
|
||||
|
||||
printf "\nsource /opt/ros/melodic/setup.bash\n" >> ~/.bashrc
|
||||
|
||||
# 1.5 Initialize rosdep
|
||||
sudo rosdep init
|
||||
rosdep update
|
||||
|
||||
|
||||
# 1.7 Getting rosinstall (python)
|
||||
sudo apt-get install python-rosinstall
|
||||
sudo apt-get install python-catkin-tools
|
||||
sudo apt-get install python-rospy
|
||||
sudo apt-get install python-rosdep
|
||||
sudo apt-get install python-roscd
|
||||
sudo apt-get install python-pip
|
||||
@@ -0,0 +1,33 @@
|
||||
#@title { display-mode: "code" }
|
||||
|
||||
#from http://wiki.ros.org/indigo/Installation/Ubuntu
|
||||
|
||||
#1.2 Setup sources.list
|
||||
sudo sh -c 'echo "deb http://packages.ros.org/ros/ubuntu $(lsb_release -sc) main" > /etc/apt/sources.list.d/ros-latest.list'
|
||||
|
||||
# 1.3 Setup keys
|
||||
sudo apt-key adv --keyserver 'hkp://keyserver.ubuntu.com:80' --recv-key C1CF6E31E6BADE8868B172B4F42ED6FBAB17C654
|
||||
|
||||
curl -sSL 'http://keyserver.ubuntu.com/pks/lookup?op=get&search=0xC1CF6E31E6BADE8868B172B4F42ED6FBAB17C654' | sudo apt-key add -
|
||||
|
||||
# 1.4 Installation
|
||||
sudo apt-get update
|
||||
sudo apt-get upgrade
|
||||
|
||||
# Desktop-Full Install:
|
||||
sudo apt-get install ros-noetic-desktop-full
|
||||
|
||||
printf "\nsource /opt/ros/noetic/setup.bash\n" >> ~/.bashrc
|
||||
|
||||
# 1.5 Initialize rosdep
|
||||
sudo rosdep init
|
||||
rosdep update
|
||||
|
||||
|
||||
# 1.7 Getting rosinstall (python)
|
||||
sudo apt-get install python3-rosinstall
|
||||
sudo apt-get install python3-catkin-tools
|
||||
sudo apt-get install python3-rospy
|
||||
sudo apt-get install python3-rosdep
|
||||
sudo apt-get install python3-roscd
|
||||
sudo apt-get install python3-pip
|
||||
@@ -0,0 +1,16 @@
|
||||
cd ~/catkin_ws/src
|
||||
catkin_create_pkg midas_cpp std_msgs roscpp cv_bridge sensor_msgs image_transport
|
||||
cd ~/catkin_ws
|
||||
catkin_make
|
||||
|
||||
chmod +x ~/catkin_ws/devel/setup.bash
|
||||
printf "\nsource ~/catkin_ws/devel/setup.bash" >> ~/.bashrc
|
||||
source ~/catkin_ws/devel/setup.bash
|
||||
|
||||
|
||||
sudo rosdep init
|
||||
rosdep update
|
||||
#rospack depends1 midas_cpp
|
||||
roscd midas_cpp
|
||||
#cat package.xml
|
||||
#rospack depends midas_cpp
|
||||
@@ -0,0 +1,2 @@
|
||||
source ~/catkin_ws/devel/setup.bash
|
||||
roslaunch midas_cpp midas_cpp.launch model_name:="model-small-traced.pt" input_topic:="image_topic" output_topic:="midas_topic" out_orig_size:="true"
|
||||
@@ -0,0 +1,189 @@
|
||||
cmake_minimum_required(VERSION 3.0.2)
|
||||
project(midas_cpp)
|
||||
|
||||
## Compile as C++11, supported in ROS Kinetic and newer
|
||||
# add_compile_options(-std=c++11)
|
||||
|
||||
## Find catkin macros and libraries
|
||||
## if COMPONENTS list like find_package(catkin REQUIRED COMPONENTS xyz)
|
||||
## is used, also find other catkin packages
|
||||
find_package(catkin REQUIRED COMPONENTS
|
||||
cv_bridge
|
||||
image_transport
|
||||
roscpp
|
||||
rospy
|
||||
sensor_msgs
|
||||
std_msgs
|
||||
)
|
||||
|
||||
## System dependencies are found with CMake's conventions
|
||||
# find_package(Boost REQUIRED COMPONENTS system)
|
||||
|
||||
list(APPEND CMAKE_PREFIX_PATH "~/libtorch")
|
||||
list(APPEND CMAKE_PREFIX_PATH "/usr/local/lib/python3.6/dist-packages/torch/lib")
|
||||
list(APPEND CMAKE_PREFIX_PATH "/usr/local/lib/python2.7/dist-packages/torch/lib")
|
||||
|
||||
if(NOT EXISTS "~/libtorch")
|
||||
if (EXISTS "/usr/local/lib/python3.6/dist-packages/torch")
|
||||
include_directories(/usr/local/include)
|
||||
include_directories(/usr/local/lib/python3.6/dist-packages/torch/include/torch/csrc/api/include)
|
||||
include_directories(/usr/local/lib/python3.6/dist-packages/torch/include)
|
||||
|
||||
link_directories(/usr/local/lib)
|
||||
link_directories(/usr/local/lib/python3.6/dist-packages/torch/lib)
|
||||
|
||||
set(CMAKE_PREFIX_PATH /usr/local/lib/python3.6/dist-packages/torch)
|
||||
set(Boost_USE_MULTITHREADED ON)
|
||||
set(Torch_DIR /usr/local/lib/python3.6/dist-packages/torch)
|
||||
|
||||
elseif (EXISTS "/usr/local/lib/python2.7/dist-packages/torch")
|
||||
|
||||
include_directories(/usr/local/include)
|
||||
include_directories(/usr/local/lib/python2.7/dist-packages/torch/include/torch/csrc/api/include)
|
||||
include_directories(/usr/local/lib/python2.7/dist-packages/torch/include)
|
||||
|
||||
link_directories(/usr/local/lib)
|
||||
link_directories(/usr/local/lib/python2.7/dist-packages/torch/lib)
|
||||
|
||||
set(CMAKE_PREFIX_PATH /usr/local/lib/python2.7/dist-packages/torch)
|
||||
set(Boost_USE_MULTITHREADED ON)
|
||||
set(Torch_DIR /usr/local/lib/python2.7/dist-packages/torch)
|
||||
endif()
|
||||
endif()
|
||||
|
||||
|
||||
|
||||
find_package(Torch REQUIRED)
|
||||
find_package(OpenCV REQUIRED)
|
||||
include_directories( ${OpenCV_INCLUDE_DIRS} )
|
||||
|
||||
add_executable(midas_cpp src/main.cpp)
|
||||
target_link_libraries(midas_cpp "${TORCH_LIBRARIES}" "${OpenCV_LIBS} ${catkin_LIBRARIES}")
|
||||
set_property(TARGET midas_cpp PROPERTY CXX_STANDARD 14)
|
||||
|
||||
|
||||
|
||||
###################################
|
||||
## catkin specific configuration ##
|
||||
###################################
|
||||
## The catkin_package macro generates cmake config files for your package
|
||||
## Declare things to be passed to dependent projects
|
||||
## INCLUDE_DIRS: uncomment this if your package contains header files
|
||||
## LIBRARIES: libraries you create in this project that dependent projects also need
|
||||
## CATKIN_DEPENDS: catkin_packages dependent projects also need
|
||||
## DEPENDS: system dependencies of this project that dependent projects also need
|
||||
catkin_package(
|
||||
# INCLUDE_DIRS include
|
||||
# LIBRARIES midas_cpp
|
||||
# CATKIN_DEPENDS cv_bridge image_transport roscpp sensor_msgs std_msgs
|
||||
# DEPENDS system_lib
|
||||
)
|
||||
|
||||
###########
|
||||
## Build ##
|
||||
###########
|
||||
|
||||
## Specify additional locations of header files
|
||||
## Your package locations should be listed before other locations
|
||||
include_directories(
|
||||
# include
|
||||
${catkin_INCLUDE_DIRS}
|
||||
)
|
||||
|
||||
## Declare a C++ library
|
||||
# add_library(${PROJECT_NAME}
|
||||
# src/${PROJECT_NAME}/midas_cpp.cpp
|
||||
# )
|
||||
|
||||
## Add cmake target dependencies of the library
|
||||
## as an example, code may need to be generated before libraries
|
||||
## either from message generation or dynamic reconfigure
|
||||
# add_dependencies(${PROJECT_NAME} ${${PROJECT_NAME}_EXPORTED_TARGETS} ${catkin_EXPORTED_TARGETS})
|
||||
|
||||
## Declare a C++ executable
|
||||
## With catkin_make all packages are built within a single CMake context
|
||||
## The recommended prefix ensures that target names across packages don't collide
|
||||
# add_executable(${PROJECT_NAME}_node src/midas_cpp_node.cpp)
|
||||
|
||||
## Rename C++ executable without prefix
|
||||
## The above recommended prefix causes long target names, the following renames the
|
||||
## target back to the shorter version for ease of user use
|
||||
## e.g. "rosrun someones_pkg node" instead of "rosrun someones_pkg someones_pkg_node"
|
||||
# set_target_properties(${PROJECT_NAME}_node PROPERTIES OUTPUT_NAME node PREFIX "")
|
||||
|
||||
## Add cmake target dependencies of the executable
|
||||
## same as for the library above
|
||||
# add_dependencies(${PROJECT_NAME}_node ${${PROJECT_NAME}_EXPORTED_TARGETS} ${catkin_EXPORTED_TARGETS})
|
||||
|
||||
## Specify libraries to link a library or executable target against
|
||||
# target_link_libraries(${PROJECT_NAME}_node
|
||||
# ${catkin_LIBRARIES}
|
||||
# )
|
||||
|
||||
#############
|
||||
## Install ##
|
||||
#############
|
||||
|
||||
# all install targets should use catkin DESTINATION variables
|
||||
# See http://ros.org/doc/api/catkin/html/adv_user_guide/variables.html
|
||||
|
||||
## Mark executable scripts (Python etc.) for installation
|
||||
## in contrast to setup.py, you can choose the destination
|
||||
# catkin_install_python(PROGRAMS
|
||||
# scripts/my_python_script
|
||||
# DESTINATION ${CATKIN_PACKAGE_BIN_DESTINATION}
|
||||
# )
|
||||
|
||||
## Mark executables for installation
|
||||
## See http://docs.ros.org/melodic/api/catkin/html/howto/format1/building_executables.html
|
||||
# install(TARGETS ${PROJECT_NAME}_node
|
||||
# RUNTIME DESTINATION ${CATKIN_PACKAGE_BIN_DESTINATION}
|
||||
# )
|
||||
|
||||
## Mark libraries for installation
|
||||
## See http://docs.ros.org/melodic/api/catkin/html/howto/format1/building_libraries.html
|
||||
# install(TARGETS ${PROJECT_NAME}
|
||||
# ARCHIVE DESTINATION ${CATKIN_PACKAGE_LIB_DESTINATION}
|
||||
# LIBRARY DESTINATION ${CATKIN_PACKAGE_LIB_DESTINATION}
|
||||
# RUNTIME DESTINATION ${CATKIN_GLOBAL_BIN_DESTINATION}
|
||||
# )
|
||||
|
||||
## Mark cpp header files for installation
|
||||
# install(DIRECTORY include/${PROJECT_NAME}/
|
||||
# DESTINATION ${CATKIN_PACKAGE_INCLUDE_DESTINATION}
|
||||
# FILES_MATCHING PATTERN "*.h"
|
||||
# PATTERN ".svn" EXCLUDE
|
||||
# )
|
||||
|
||||
## Mark other files for installation (e.g. launch and bag files, etc.)
|
||||
# install(FILES
|
||||
# # myfile1
|
||||
# # myfile2
|
||||
# DESTINATION ${CATKIN_PACKAGE_SHARE_DESTINATION}
|
||||
# )
|
||||
|
||||
#############
|
||||
## Testing ##
|
||||
#############
|
||||
|
||||
## Add gtest based cpp test target and link libraries
|
||||
# catkin_add_gtest(${PROJECT_NAME}-test test/test_midas_cpp.cpp)
|
||||
# if(TARGET ${PROJECT_NAME}-test)
|
||||
# target_link_libraries(${PROJECT_NAME}-test ${PROJECT_NAME})
|
||||
# endif()
|
||||
|
||||
## Add folders to be run by python nosetests
|
||||
# catkin_add_nosetests(test)
|
||||
|
||||
install(TARGETS ${PROJECT_NAME}
|
||||
ARCHIVE DESTINATION ${CATKIN_PACKAGE_LIB_DESTINATION}
|
||||
LIBRARY DESTINATION ${CATKIN_PACKAGE_LIB_DESTINATION}
|
||||
RUNTIME DESTINATION ${CATKIN_PACKAGE_BIN_DESTINATION}
|
||||
)
|
||||
|
||||
add_custom_command(
|
||||
TARGET midas_cpp POST_BUILD
|
||||
COMMAND ${CMAKE_COMMAND} -E copy
|
||||
${CMAKE_CURRENT_BINARY_DIR}/midas_cpp
|
||||
${CMAKE_SOURCE_DIR}/midas_cpp
|
||||
)
|
||||
@@ -0,0 +1,19 @@
|
||||
<launch>
|
||||
<arg name="input_topic" default="image_topic"/>
|
||||
<arg name="output_topic" default="midas_topic"/>
|
||||
<arg name="model_name" default="model-small-traced.pt"/>
|
||||
<arg name="out_orig_size" default="true"/>
|
||||
<arg name="net_width" default="256"/>
|
||||
<arg name="net_height" default="256"/>
|
||||
<arg name="logging" default="false"/>
|
||||
|
||||
<node pkg="midas_cpp" type="midas_cpp" name="midas_cpp" output="log" respawn="true">
|
||||
<param name="input_topic" value="$(arg input_topic)"/>
|
||||
<param name="output_topic" value="$(arg output_topic)"/>
|
||||
<param name="model_name" value="$(arg model_name)"/>
|
||||
<param name="out_orig_size" value="$(arg out_orig_size)"/>
|
||||
<param name="net_width" value="$(arg net_width)"/>
|
||||
<param name="net_height" value="$(arg net_height)"/>
|
||||
<param name="logging" value="$(arg logging)"/>
|
||||
</node>
|
||||
</launch>
|
||||
@@ -0,0 +1,23 @@
|
||||
<launch>
|
||||
<arg name="use_camera" default="false"/>
|
||||
<arg name="input_video_file" default="test.mp4"/>
|
||||
|
||||
<arg name="show_output" default="true"/>
|
||||
<arg name="save_output" default="false"/>
|
||||
<arg name="output_video_file" default="result.mp4"/>
|
||||
|
||||
<node pkg="midas_cpp" type="talker.py" name="talker" output="log" respawn="true">
|
||||
<param name="use_camera" value="$(arg use_camera)"/>
|
||||
<param name="input_video_file" value="$(arg input_video_file)"/>
|
||||
</node>
|
||||
|
||||
<node pkg="midas_cpp" type="listener.py" name="listener" output="log" respawn="true">
|
||||
<param name="show_output" value="$(arg show_output)"/>
|
||||
<param name="save_output" value="$(arg save_output)"/>
|
||||
<param name="output_video_file" value="$(arg output_video_file)"/>
|
||||
</node>
|
||||
|
||||
<node pkg="midas_cpp" type="listener_original.py" name="listener_original" output="log" respawn="true">
|
||||
<param name="show_output" value="$(arg show_output)"/>
|
||||
</node>
|
||||
</launch>
|
||||
@@ -0,0 +1,77 @@
|
||||
<?xml version="1.0"?>
|
||||
<package format="2">
|
||||
<name>midas_cpp</name>
|
||||
<version>0.1.0</version>
|
||||
<description>The midas_cpp package</description>
|
||||
|
||||
<maintainer email="alexeyab84@gmail.com">Alexey Bochkovskiy</maintainer>
|
||||
<license>MIT</license>
|
||||
<url type="website">https://github.com/isl-org/MiDaS/tree/master/ros</url>
|
||||
<!-- <author email="alexeyab84@gmail.com">Alexey Bochkovskiy</author> -->
|
||||
|
||||
|
||||
<!-- One license tag required, multiple allowed, one license per tag -->
|
||||
<!-- Commonly used license strings: -->
|
||||
<!-- BSD, MIT, Boost Software License, GPLv2, GPLv3, LGPLv2.1, LGPLv3 -->
|
||||
<license>TODO</license>
|
||||
|
||||
|
||||
<!-- Url tags are optional, but multiple are allowed, one per tag -->
|
||||
<!-- Optional attribute type can be: website, bugtracker, or repository -->
|
||||
<!-- Example: -->
|
||||
<!-- <url type="website">http://wiki.ros.org/midas_cpp</url> -->
|
||||
|
||||
|
||||
<!-- Author tags are optional, multiple are allowed, one per tag -->
|
||||
<!-- Authors do not have to be maintainers, but could be -->
|
||||
<!-- Example: -->
|
||||
<!-- <author email="jane.doe@example.com">Jane Doe</author> -->
|
||||
|
||||
|
||||
<!-- The *depend tags are used to specify dependencies -->
|
||||
<!-- Dependencies can be catkin packages or system dependencies -->
|
||||
<!-- Examples: -->
|
||||
<!-- Use depend as a shortcut for packages that are both build and exec dependencies -->
|
||||
<!-- <depend>roscpp</depend> -->
|
||||
<!-- Note that this is equivalent to the following: -->
|
||||
<!-- <build_depend>roscpp</build_depend> -->
|
||||
<!-- <exec_depend>roscpp</exec_depend> -->
|
||||
<!-- Use build_depend for packages you need at compile time: -->
|
||||
<!-- <build_depend>message_generation</build_depend> -->
|
||||
<!-- Use build_export_depend for packages you need in order to build against this package: -->
|
||||
<!-- <build_export_depend>message_generation</build_export_depend> -->
|
||||
<!-- Use buildtool_depend for build tool packages: -->
|
||||
<!-- <buildtool_depend>catkin</buildtool_depend> -->
|
||||
<!-- Use exec_depend for packages you need at runtime: -->
|
||||
<!-- <exec_depend>message_runtime</exec_depend> -->
|
||||
<!-- Use test_depend for packages you need only for testing: -->
|
||||
<!-- <test_depend>gtest</test_depend> -->
|
||||
<!-- Use doc_depend for packages you need only for building documentation: -->
|
||||
<!-- <doc_depend>doxygen</doc_depend> -->
|
||||
<buildtool_depend>catkin</buildtool_depend>
|
||||
<build_depend>cv_bridge</build_depend>
|
||||
<build_depend>image_transport</build_depend>
|
||||
<build_depend>roscpp</build_depend>
|
||||
<build_depend>rospy</build_depend>
|
||||
<build_depend>sensor_msgs</build_depend>
|
||||
<build_depend>std_msgs</build_depend>
|
||||
<build_export_depend>cv_bridge</build_export_depend>
|
||||
<build_export_depend>image_transport</build_export_depend>
|
||||
<build_export_depend>roscpp</build_export_depend>
|
||||
<build_export_depend>rospy</build_export_depend>
|
||||
<build_export_depend>sensor_msgs</build_export_depend>
|
||||
<build_export_depend>std_msgs</build_export_depend>
|
||||
<exec_depend>cv_bridge</exec_depend>
|
||||
<exec_depend>image_transport</exec_depend>
|
||||
<exec_depend>roscpp</exec_depend>
|
||||
<exec_depend>rospy</exec_depend>
|
||||
<exec_depend>sensor_msgs</exec_depend>
|
||||
<exec_depend>std_msgs</exec_depend>
|
||||
|
||||
|
||||
<!-- The export tag contains other, unspecified, tags -->
|
||||
<export>
|
||||
<!-- Other tools can request additional information be placed here -->
|
||||
|
||||
</export>
|
||||
</package>
|
||||
@@ -0,0 +1,63 @@
|
||||
#!/usr/bin/env python3
|
||||
from __future__ import print_function
|
||||
|
||||
#roslib.load_manifest('my_package')
|
||||
import sys
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import roslib
|
||||
import rospy
|
||||
from cv_bridge import CvBridge, CvBridgeError
|
||||
from sensor_msgs.msg import Image
|
||||
from std_msgs.msg import String
|
||||
|
||||
|
||||
class video_show:
|
||||
|
||||
def __init__(self):
|
||||
self.show_output = rospy.get_param('~show_output', True)
|
||||
self.save_output = rospy.get_param('~save_output', False)
|
||||
self.output_video_file = rospy.get_param('~output_video_file','result.mp4')
|
||||
# rospy.loginfo(f"Listener - params: show_output={self.show_output}, save_output={self.save_output}, output_video_file={self.output_video_file}")
|
||||
|
||||
self.bridge = CvBridge()
|
||||
self.image_sub = rospy.Subscriber("midas_topic", Image, self.callback)
|
||||
|
||||
def callback(self, data):
|
||||
try:
|
||||
cv_image = self.bridge.imgmsg_to_cv2(data)
|
||||
except CvBridgeError as e:
|
||||
print(e)
|
||||
return
|
||||
|
||||
if cv_image.size == 0:
|
||||
return
|
||||
|
||||
rospy.loginfo("Listener: Received new frame")
|
||||
cv_image = cv_image.astype("uint8")
|
||||
|
||||
if self.show_output==True:
|
||||
cv2.imshow("video_show", cv_image)
|
||||
cv2.waitKey(10)
|
||||
|
||||
if self.save_output==True:
|
||||
if self.video_writer_init==False:
|
||||
fourcc = cv2.VideoWriter_fourcc(*'XVID')
|
||||
self.out = cv2.VideoWriter(self.output_video_file, fourcc, 25, (cv_image.shape[1], cv_image.shape[0]))
|
||||
|
||||
self.out.write(cv_image)
|
||||
|
||||
|
||||
|
||||
def main(args):
|
||||
rospy.init_node('listener', anonymous=True)
|
||||
ic = video_show()
|
||||
try:
|
||||
rospy.spin()
|
||||
except KeyboardInterrupt:
|
||||
print("Shutting down")
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
if __name__ == '__main__':
|
||||
main(sys.argv)
|
||||
@@ -0,0 +1,63 @@
|
||||
#!/usr/bin/env python3
|
||||
from __future__ import print_function
|
||||
|
||||
#roslib.load_manifest('my_package')
|
||||
import sys
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import roslib
|
||||
import rospy
|
||||
from cv_bridge import CvBridge, CvBridgeError
|
||||
from sensor_msgs.msg import Image
|
||||
from std_msgs.msg import String
|
||||
|
||||
|
||||
class video_show:
|
||||
|
||||
def __init__(self):
|
||||
self.show_output = rospy.get_param('~show_output', True)
|
||||
self.save_output = rospy.get_param('~save_output', False)
|
||||
self.output_video_file = rospy.get_param('~output_video_file','result.mp4')
|
||||
# rospy.loginfo(f"Listener original - params: show_output={self.show_output}, save_output={self.save_output}, output_video_file={self.output_video_file}")
|
||||
|
||||
self.bridge = CvBridge()
|
||||
self.image_sub = rospy.Subscriber("image_topic", Image, self.callback)
|
||||
|
||||
def callback(self, data):
|
||||
try:
|
||||
cv_image = self.bridge.imgmsg_to_cv2(data)
|
||||
except CvBridgeError as e:
|
||||
print(e)
|
||||
return
|
||||
|
||||
if cv_image.size == 0:
|
||||
return
|
||||
|
||||
rospy.loginfo("Listener_original: Received new frame")
|
||||
cv_image = cv_image.astype("uint8")
|
||||
|
||||
if self.show_output==True:
|
||||
cv2.imshow("video_show_orig", cv_image)
|
||||
cv2.waitKey(10)
|
||||
|
||||
if self.save_output==True:
|
||||
if self.video_writer_init==False:
|
||||
fourcc = cv2.VideoWriter_fourcc(*'XVID')
|
||||
self.out = cv2.VideoWriter(self.output_video_file, fourcc, 25, (cv_image.shape[1], cv_image.shape[0]))
|
||||
|
||||
self.out.write(cv_image)
|
||||
|
||||
|
||||
|
||||
def main(args):
|
||||
rospy.init_node('listener_original', anonymous=True)
|
||||
ic = video_show()
|
||||
try:
|
||||
rospy.spin()
|
||||
except KeyboardInterrupt:
|
||||
print("Shutting down")
|
||||
cv2.destroyAllWindows()
|
||||
|
||||
if __name__ == '__main__':
|
||||
main(sys.argv)
|
||||
@@ -0,0 +1,54 @@
|
||||
#!/usr/bin/env python3
|
||||
|
||||
|
||||
#roslib.load_manifest('my_package')
|
||||
import sys
|
||||
|
||||
import cv2
|
||||
import roslib
|
||||
import rospy
|
||||
from cv_bridge import CvBridge, CvBridgeError
|
||||
from sensor_msgs.msg import Image
|
||||
from std_msgs.msg import String
|
||||
|
||||
|
||||
def talker():
|
||||
rospy.init_node('talker', anonymous=True)
|
||||
|
||||
use_camera = rospy.get_param('~use_camera', False)
|
||||
input_video_file = rospy.get_param('~input_video_file','test.mp4')
|
||||
# rospy.loginfo(f"Talker - params: use_camera={use_camera}, input_video_file={input_video_file}")
|
||||
|
||||
# rospy.loginfo("Talker: Trying to open a video stream")
|
||||
if use_camera == True:
|
||||
cap = cv2.VideoCapture(0)
|
||||
else:
|
||||
cap = cv2.VideoCapture(input_video_file)
|
||||
|
||||
pub = rospy.Publisher('image_topic', Image, queue_size=1)
|
||||
rate = rospy.Rate(30) # 30hz
|
||||
bridge = CvBridge()
|
||||
|
||||
while not rospy.is_shutdown():
|
||||
ret, cv_image = cap.read()
|
||||
if ret==False:
|
||||
print("Talker: Video is over")
|
||||
rospy.loginfo("Video is over")
|
||||
return
|
||||
|
||||
try:
|
||||
image = bridge.cv2_to_imgmsg(cv_image, "bgr8")
|
||||
except CvBridgeError as e:
|
||||
rospy.logerr("Talker: cv2image conversion failed: ", e)
|
||||
print(e)
|
||||
continue
|
||||
|
||||
rospy.loginfo("Talker: Publishing frame")
|
||||
pub.publish(image)
|
||||
rate.sleep()
|
||||
|
||||
if __name__ == '__main__':
|
||||
try:
|
||||
talker()
|
||||
except rospy.ROSInterruptException:
|
||||
pass
|
||||
@@ -0,0 +1,285 @@
|
||||
#include <ros/ros.h>
|
||||
#include <image_transport/image_transport.h>
|
||||
#include <cv_bridge/cv_bridge.h>
|
||||
#include <sensor_msgs/image_encodings.h>
|
||||
|
||||
#include <initializer_list>
|
||||
|
||||
#include <torch/script.h> // One-stop header.
|
||||
|
||||
#include <opencv2/core/version.hpp>
|
||||
#include <opencv2/imgproc/imgproc.hpp>
|
||||
#include <opencv2/opencv.hpp>
|
||||
#include <opencv2/opencv_modules.hpp>
|
||||
|
||||
#include <opencv2/highgui/highgui.hpp>
|
||||
#include <opencv2/video/video.hpp>
|
||||
|
||||
// includes for OpenCV >= 3.x
|
||||
#ifndef CV_VERSION_EPOCH
|
||||
#include <opencv2/core/types.hpp>
|
||||
#include <opencv2/videoio/videoio.hpp>
|
||||
#include <opencv2/imgcodecs/imgcodecs.hpp>
|
||||
#endif
|
||||
|
||||
// OpenCV includes for OpenCV 2.x
|
||||
#ifdef CV_VERSION_EPOCH
|
||||
#include <opencv2/highgui/highgui_c.h>
|
||||
#include <opencv2/imgproc/imgproc_c.h>
|
||||
#include <opencv2/core/types_c.h>
|
||||
#include <opencv2/core/version.hpp>
|
||||
#endif
|
||||
|
||||
static const std::string OPENCV_WINDOW = "Image window";
|
||||
|
||||
class Midas
|
||||
{
|
||||
ros::NodeHandle nh_;
|
||||
image_transport::ImageTransport it_;
|
||||
image_transport::Subscriber image_sub_;
|
||||
image_transport::Publisher image_pub_;
|
||||
|
||||
torch::jit::script::Module module;
|
||||
torch::Device device;
|
||||
|
||||
auto ToTensor(cv::Mat img, bool show_output = false, bool unsqueeze = false, int unsqueeze_dim = 0)
|
||||
{
|
||||
//std::cout << "image shape: " << img.size() << std::endl;
|
||||
at::Tensor tensor_image = torch::from_blob(img.data, { img.rows, img.cols, 3 }, at::kByte);
|
||||
|
||||
if (unsqueeze)
|
||||
{
|
||||
tensor_image.unsqueeze_(unsqueeze_dim);
|
||||
//std::cout << "tensors new shape: " << tensor_image.sizes() << std::endl;
|
||||
}
|
||||
|
||||
if (show_output)
|
||||
{
|
||||
std::cout << tensor_image.slice(2, 0, 1) << std::endl;
|
||||
}
|
||||
//std::cout << "tenor shape: " << tensor_image.sizes() << std::endl;
|
||||
return tensor_image;
|
||||
}
|
||||
|
||||
auto ToInput(at::Tensor tensor_image)
|
||||
{
|
||||
// Create a vector of inputs.
|
||||
return std::vector<torch::jit::IValue>{tensor_image};
|
||||
}
|
||||
|
||||
auto ToCvImage(at::Tensor tensor, int cv_type = CV_8UC3)
|
||||
{
|
||||
int width = tensor.sizes()[0];
|
||||
int height = tensor.sizes()[1];
|
||||
try
|
||||
{
|
||||
cv::Mat output_mat;
|
||||
if (cv_type == CV_8UC4 || cv_type == CV_8UC3 || cv_type == CV_8UC2 || cv_type == CV_8UC1) {
|
||||
cv::Mat cv_image(cv::Size{ height, width }, cv_type, tensor.data_ptr<uchar>());
|
||||
output_mat = cv_image;
|
||||
}
|
||||
else if (cv_type == CV_32FC4 || cv_type == CV_32FC3 || cv_type == CV_32FC2 || cv_type == CV_32FC1) {
|
||||
cv::Mat cv_image(cv::Size{ height, width }, cv_type, tensor.data_ptr<float>());
|
||||
output_mat = cv_image;
|
||||
}
|
||||
else if (cv_type == CV_64FC4 || cv_type == CV_64FC3 || cv_type == CV_64FC2 || cv_type == CV_64FC1) {
|
||||
cv::Mat cv_image(cv::Size{ height, width }, cv_type, tensor.data_ptr<double>());
|
||||
output_mat = cv_image;
|
||||
}
|
||||
|
||||
//show_image(output_mat, "converted image from tensor");
|
||||
return output_mat.clone();
|
||||
}
|
||||
catch (const c10::Error& e)
|
||||
{
|
||||
std::cout << "an error has occured : " << e.msg() << std::endl;
|
||||
}
|
||||
return cv::Mat(height, width, CV_8UC3);
|
||||
}
|
||||
|
||||
std::string input_topic, output_topic, model_name;
|
||||
bool out_orig_size;
|
||||
int net_width, net_height;
|
||||
torch::NoGradGuard guard;
|
||||
at::Tensor mean, std;
|
||||
at::Tensor output, tensor;
|
||||
|
||||
public:
|
||||
Midas()
|
||||
: nh_(), it_(nh_), device(torch::Device(torch::kCPU))
|
||||
{
|
||||
ros::param::param<std::string>("~input_topic", input_topic, "image_topic");
|
||||
ros::param::param<std::string>("~output_topic", output_topic, "midas_topic");
|
||||
ros::param::param<std::string>("~model_name", model_name, "model-small-traced.pt");
|
||||
ros::param::param<bool>("~out_orig_size", out_orig_size, true);
|
||||
ros::param::param<int>("~net_width", net_width, 256);
|
||||
ros::param::param<int>("~net_height", net_height, 256);
|
||||
|
||||
std::cout << ", input_topic = " << input_topic <<
|
||||
", output_topic = " << output_topic <<
|
||||
", model_name = " << model_name <<
|
||||
", out_orig_size = " << out_orig_size <<
|
||||
", net_width = " << net_width <<
|
||||
", net_height = " << net_height <<
|
||||
std::endl;
|
||||
|
||||
// Subscrive to input video feed and publish output video feed
|
||||
image_sub_ = it_.subscribe(input_topic, 1, &Midas::imageCb, this);
|
||||
image_pub_ = it_.advertise(output_topic, 1);
|
||||
|
||||
std::cout << "Try to load torchscript model \n";
|
||||
|
||||
try {
|
||||
// Deserialize the ScriptModule from a file using torch::jit::load().
|
||||
module = torch::jit::load(model_name);
|
||||
}
|
||||
catch (const c10::Error& e) {
|
||||
std::cerr << "error loading the model\n";
|
||||
exit(0);
|
||||
}
|
||||
|
||||
std::cout << "ok\n";
|
||||
|
||||
try {
|
||||
module.eval();
|
||||
torch::jit::getProfilingMode() = false;
|
||||
torch::jit::setGraphExecutorOptimize(true);
|
||||
|
||||
mean = torch::tensor({ 0.485, 0.456, 0.406 });
|
||||
std = torch::tensor({ 0.229, 0.224, 0.225 });
|
||||
|
||||
if (torch::hasCUDA()) {
|
||||
std::cout << "cuda is available" << std::endl;
|
||||
at::globalContext().setBenchmarkCuDNN(true);
|
||||
device = torch::Device(torch::kCUDA);
|
||||
module.to(device);
|
||||
mean = mean.to(device);
|
||||
std = std.to(device);
|
||||
}
|
||||
}
|
||||
catch (const c10::Error& e)
|
||||
{
|
||||
std::cerr << " module initialization: " << e.msg() << std::endl;
|
||||
}
|
||||
}
|
||||
|
||||
~Midas()
|
||||
{
|
||||
}
|
||||
|
||||
void imageCb(const sensor_msgs::ImageConstPtr& msg)
|
||||
{
|
||||
cv_bridge::CvImagePtr cv_ptr;
|
||||
try
|
||||
{
|
||||
// sensor_msgs::Image to cv::Mat
|
||||
cv_ptr = cv_bridge::toCvCopy(msg, sensor_msgs::image_encodings::RGB8);
|
||||
}
|
||||
catch (cv_bridge::Exception& e)
|
||||
{
|
||||
ROS_ERROR("cv_bridge exception: %s", e.what());
|
||||
return;
|
||||
}
|
||||
|
||||
// pre-processing
|
||||
auto tensor_cpu = ToTensor(cv_ptr->image); // OpenCV-image -> Libtorch-tensor
|
||||
|
||||
try {
|
||||
tensor = tensor_cpu.to(device); // move to device (CPU or GPU)
|
||||
|
||||
tensor = tensor.toType(c10::kFloat);
|
||||
tensor = tensor.permute({ 2, 0, 1 }); // HWC -> CHW
|
||||
tensor = tensor.unsqueeze(0);
|
||||
tensor = at::upsample_bilinear2d(tensor, { net_height, net_width }, true); // resize
|
||||
tensor = tensor.squeeze(0);
|
||||
tensor = tensor.permute({ 1, 2, 0 }); // CHW -> HWC
|
||||
|
||||
tensor = tensor.div(255).sub(mean).div(std); // normalization
|
||||
tensor = tensor.permute({ 2, 0, 1 }); // HWC -> CHW
|
||||
tensor.unsqueeze_(0); // CHW -> NCHW
|
||||
}
|
||||
catch (const c10::Error& e)
|
||||
{
|
||||
std::cerr << " pre-processing exception: " << e.msg() << std::endl;
|
||||
return;
|
||||
}
|
||||
|
||||
auto input_to_net = ToInput(tensor); // input to the network
|
||||
|
||||
// inference
|
||||
output;
|
||||
try {
|
||||
output = module.forward(input_to_net).toTensor(); // run inference
|
||||
}
|
||||
catch (const c10::Error& e)
|
||||
{
|
||||
std::cerr << " module.forward() exception: " << e.msg() << std::endl;
|
||||
return;
|
||||
}
|
||||
|
||||
output = output.detach().to(torch::kF32);
|
||||
|
||||
// move to CPU temporary
|
||||
at::Tensor output_tmp = output;
|
||||
output_tmp = output_tmp.to(torch::kCPU);
|
||||
|
||||
// normalization
|
||||
float min_val = std::numeric_limits<float>::max();
|
||||
float max_val = std::numeric_limits<float>::min();
|
||||
|
||||
for (int i = 0; i < net_width * net_height; ++i) {
|
||||
float val = output_tmp.data_ptr<float>()[i];
|
||||
if (min_val > val) min_val = val;
|
||||
if (max_val < val) max_val = val;
|
||||
}
|
||||
float range_val = max_val - min_val;
|
||||
|
||||
output = output.sub(min_val).div(range_val).mul(255.0F).clamp(0, 255).to(torch::kF32); // .to(torch::kU8);
|
||||
|
||||
// resize to the original size if required
|
||||
if (out_orig_size) {
|
||||
try {
|
||||
output = at::upsample_bilinear2d(output.unsqueeze(0), { cv_ptr->image.size().height, cv_ptr->image.size().width }, true);
|
||||
output = output.squeeze(0);
|
||||
}
|
||||
catch (const c10::Error& e)
|
||||
{
|
||||
std::cout << " upsample_bilinear2d() exception: " << e.msg() << std::endl;
|
||||
return;
|
||||
}
|
||||
}
|
||||
output = output.permute({ 1, 2, 0 }).to(torch::kCPU);
|
||||
|
||||
int cv_type = CV_32FC1; // CV_8UC1;
|
||||
auto cv_img = ToCvImage(output, cv_type);
|
||||
|
||||
sensor_msgs::Image img_msg;
|
||||
|
||||
try {
|
||||
// cv::Mat -> sensor_msgs::Image
|
||||
std_msgs::Header header; // empty header
|
||||
header.seq = 0; // user defined counter
|
||||
header.stamp = ros::Time::now();// time
|
||||
//cv_bridge::CvImage img_bridge = cv_bridge::CvImage(header, sensor_msgs::image_encodings::MONO8, cv_img);
|
||||
cv_bridge::CvImage img_bridge = cv_bridge::CvImage(header, sensor_msgs::image_encodings::TYPE_32FC1, cv_img);
|
||||
|
||||
img_bridge.toImageMsg(img_msg); // cv_bridge -> sensor_msgs::Image
|
||||
}
|
||||
catch (cv_bridge::Exception& e)
|
||||
{
|
||||
ROS_ERROR("cv_bridge exception: %s", e.what());
|
||||
return;
|
||||
}
|
||||
|
||||
// Output modified video stream
|
||||
image_pub_.publish(img_msg);
|
||||
}
|
||||
};
|
||||
|
||||
int main(int argc, char** argv)
|
||||
{
|
||||
ros::init(argc, argv, "midas", ros::init_options::AnonymousName);
|
||||
Midas ic;
|
||||
ros::spin();
|
||||
return 0;
|
||||
}
|
||||
@@ -0,0 +1,16 @@
|
||||
# place any test.mp4 file near with this file
|
||||
|
||||
# roscore
|
||||
# rosnode kill -a
|
||||
|
||||
source ~/catkin_ws/devel/setup.bash
|
||||
|
||||
roscore &
|
||||
P1=$!
|
||||
rosrun midas_cpp talker.py &
|
||||
P2=$!
|
||||
rosrun midas_cpp listener_original.py &
|
||||
P3=$!
|
||||
rosrun midas_cpp listener.py &
|
||||
P4=$!
|
||||
wait $P1 $P2 $P3 $P4
|
||||
@@ -0,0 +1,277 @@
|
||||
"""Compute depth maps for images in the input folder.
|
||||
"""
|
||||
import argparse
|
||||
import glob
|
||||
import os
|
||||
import time
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import torch
|
||||
import utils
|
||||
from imutils.video import VideoStream
|
||||
from midas.model_loader import default_models, load_model
|
||||
from modules import devices
|
||||
|
||||
first_execution = True
|
||||
def process(device, model, model_type, image, input_size, target_size, optimize, use_camera):
|
||||
"""
|
||||
Run the inference and interpolate.
|
||||
|
||||
Args:
|
||||
device (torch.device): the torch device used
|
||||
model: the model used for inference
|
||||
model_type: the type of the model
|
||||
image: the image fed into the neural network
|
||||
input_size: the size (width, height) of the neural network input (for OpenVINO)
|
||||
target_size: the size (width, height) the neural network output is interpolated to
|
||||
optimize: optimize the model to half-floats on CUDA?
|
||||
use_camera: is the camera used?
|
||||
|
||||
Returns:
|
||||
the prediction
|
||||
"""
|
||||
global first_execution
|
||||
|
||||
if "openvino" in model_type:
|
||||
if first_execution or not use_camera:
|
||||
print(f" Input resized to {input_size[0]}x{input_size[1]} before entering the encoder")
|
||||
first_execution = False
|
||||
|
||||
sample = [np.reshape(image, (1, 3, *input_size))]
|
||||
prediction = model(sample)[model.output(0)][0]
|
||||
prediction = cv2.resize(prediction, dsize=target_size,
|
||||
interpolation=cv2.INTER_CUBIC)
|
||||
else:
|
||||
sample = torch.from_numpy(image).to(device).unsqueeze(0)
|
||||
|
||||
if optimize and device == torch.device("cuda"):
|
||||
if first_execution:
|
||||
print(" Optimization to half-floats activated. Use with caution, because models like Swin require\n"
|
||||
" float precision to work properly and may yield non-finite depth values to some extent for\n"
|
||||
" half-floats.")
|
||||
sample = sample.to(memory_format=torch.channels_last)
|
||||
sample = sample.half()
|
||||
|
||||
if first_execution or not use_camera:
|
||||
height, width = sample.shape[2:]
|
||||
print(f" Input resized to {width}x{height} before entering the encoder")
|
||||
first_execution = False
|
||||
|
||||
prediction = model.forward(sample)
|
||||
prediction = (
|
||||
torch.nn.functional.interpolate(
|
||||
prediction.unsqueeze(1),
|
||||
size=target_size[::-1],
|
||||
mode="bicubic",
|
||||
align_corners=False,
|
||||
)
|
||||
.squeeze()
|
||||
.cpu()
|
||||
.numpy()
|
||||
)
|
||||
|
||||
return prediction
|
||||
|
||||
|
||||
def create_side_by_side(image, depth, grayscale):
|
||||
"""
|
||||
Take an RGB image and depth map and place them side by side. This includes a proper normalization of the depth map
|
||||
for better visibility.
|
||||
|
||||
Args:
|
||||
image: the RGB image
|
||||
depth: the depth map
|
||||
grayscale: use a grayscale colormap?
|
||||
|
||||
Returns:
|
||||
the image and depth map place side by side
|
||||
"""
|
||||
depth_min = depth.min()
|
||||
depth_max = depth.max()
|
||||
normalized_depth = 255 * (depth - depth_min) / (depth_max - depth_min)
|
||||
normalized_depth *= 3
|
||||
|
||||
right_side = np.repeat(np.expand_dims(normalized_depth, 2), 3, axis=2) / 3
|
||||
if not grayscale:
|
||||
right_side = cv2.applyColorMap(np.uint8(right_side), cv2.COLORMAP_INFERNO)
|
||||
|
||||
if image is None:
|
||||
return right_side
|
||||
else:
|
||||
return np.concatenate((image, right_side), axis=1)
|
||||
|
||||
|
||||
def run(input_path, output_path, model_path, model_type="dpt_beit_large_512", optimize=False, side=False, height=None,
|
||||
square=False, grayscale=False):
|
||||
"""Run MonoDepthNN to compute depth maps.
|
||||
|
||||
Args:
|
||||
input_path (str): path to input folder
|
||||
output_path (str): path to output folder
|
||||
model_path (str): path to saved model
|
||||
model_type (str): the model type
|
||||
optimize (bool): optimize the model to half-floats on CUDA?
|
||||
side (bool): RGB and depth side by side in output images?
|
||||
height (int): inference encoder image height
|
||||
square (bool): resize to a square resolution?
|
||||
grayscale (bool): use a grayscale colormap?
|
||||
"""
|
||||
print("Initialize")
|
||||
|
||||
# select device
|
||||
device = devices.get_device_for("controlnet") if torch.cuda.is_available() else torch.device("cpu")
|
||||
print("Device: %s" % device)
|
||||
|
||||
model, transform, net_w, net_h = load_model(device, model_path, model_type, optimize, height, square)
|
||||
|
||||
# get input
|
||||
if input_path is not None:
|
||||
image_names = glob.glob(os.path.join(input_path, "*"))
|
||||
num_images = len(image_names)
|
||||
else:
|
||||
print("No input path specified. Grabbing images from camera.")
|
||||
|
||||
# create output folder
|
||||
if output_path is not None:
|
||||
os.makedirs(output_path, exist_ok=True)
|
||||
|
||||
print("Start processing")
|
||||
|
||||
if input_path is not None:
|
||||
if output_path is None:
|
||||
print("Warning: No output path specified. Images will be processed but not shown or stored anywhere.")
|
||||
for index, image_name in enumerate(image_names):
|
||||
|
||||
print(" Processing {} ({}/{})".format(image_name, index + 1, num_images))
|
||||
|
||||
# input
|
||||
original_image_rgb = utils.read_image(image_name) # in [0, 1]
|
||||
image = transform({"image": original_image_rgb})["image"]
|
||||
|
||||
# compute
|
||||
with torch.no_grad():
|
||||
prediction = process(device, model, model_type, image, (net_w, net_h), original_image_rgb.shape[1::-1],
|
||||
optimize, False)
|
||||
|
||||
# output
|
||||
if output_path is not None:
|
||||
filename = os.path.join(
|
||||
output_path, os.path.splitext(os.path.basename(image_name))[0] + '-' + model_type
|
||||
)
|
||||
if not side:
|
||||
utils.write_depth(filename, prediction, grayscale, bits=2)
|
||||
else:
|
||||
original_image_bgr = np.flip(original_image_rgb, 2)
|
||||
content = create_side_by_side(original_image_bgr*255, prediction, grayscale)
|
||||
cv2.imwrite(filename + ".png", content)
|
||||
utils.write_pfm(filename + ".pfm", prediction.astype(np.float32))
|
||||
|
||||
else:
|
||||
with torch.no_grad():
|
||||
fps = 1
|
||||
video = VideoStream(0).start()
|
||||
time_start = time.time()
|
||||
frame_index = 0
|
||||
while True:
|
||||
frame = video.read()
|
||||
if frame is not None:
|
||||
original_image_rgb = np.flip(frame, 2) # in [0, 255] (flip required to get RGB)
|
||||
image = transform({"image": original_image_rgb/255})["image"]
|
||||
|
||||
prediction = process(device, model, model_type, image, (net_w, net_h),
|
||||
original_image_rgb.shape[1::-1], optimize, True)
|
||||
|
||||
original_image_bgr = np.flip(original_image_rgb, 2) if side else None
|
||||
content = create_side_by_side(original_image_bgr, prediction, grayscale)
|
||||
cv2.imshow('MiDaS Depth Estimation - Press Escape to close window ', content/255)
|
||||
|
||||
if output_path is not None:
|
||||
filename = os.path.join(output_path, 'Camera' + '-' + model_type + '_' + str(frame_index))
|
||||
cv2.imwrite(filename + ".png", content)
|
||||
|
||||
alpha = 0.1
|
||||
if time.time()-time_start > 0:
|
||||
fps = (1 - alpha) * fps + alpha * 1 / (time.time()-time_start) # exponential moving average
|
||||
time_start = time.time()
|
||||
print(f"\rFPS: {round(fps,2)}", end="")
|
||||
|
||||
if cv2.waitKey(1) == 27: # Escape key
|
||||
break
|
||||
|
||||
frame_index += 1
|
||||
print()
|
||||
|
||||
print("Finished")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
|
||||
parser.add_argument('-i', '--input_path',
|
||||
default=None,
|
||||
help='Folder with input images (if no input path is specified, images are tried to be grabbed '
|
||||
'from camera)'
|
||||
)
|
||||
|
||||
parser.add_argument('-o', '--output_path',
|
||||
default=None,
|
||||
help='Folder for output images'
|
||||
)
|
||||
|
||||
parser.add_argument('-m', '--model_weights',
|
||||
default=None,
|
||||
help='Path to the trained weights of model'
|
||||
)
|
||||
|
||||
parser.add_argument('-t', '--model_type',
|
||||
default='dpt_beit_large_512',
|
||||
help='Model type: '
|
||||
'dpt_beit_large_512, dpt_beit_large_384, dpt_beit_base_384, dpt_swin2_large_384, '
|
||||
'dpt_swin2_base_384, dpt_swin2_tiny_256, dpt_swin_large_384, dpt_next_vit_large_384, '
|
||||
'dpt_levit_224, dpt_large_384, dpt_hybrid_384, midas_v21_384, midas_v21_small_256 or '
|
||||
'openvino_midas_v21_small_256'
|
||||
)
|
||||
|
||||
parser.add_argument('-s', '--side',
|
||||
action='store_true',
|
||||
help='Output images contain RGB and depth images side by side'
|
||||
)
|
||||
|
||||
parser.add_argument('--optimize', dest='optimize', action='store_true', help='Use half-float optimization')
|
||||
parser.set_defaults(optimize=False)
|
||||
|
||||
parser.add_argument('--height',
|
||||
type=int, default=None,
|
||||
help='Preferred height of images feed into the encoder during inference. Note that the '
|
||||
'preferred height may differ from the actual height, because an alignment to multiples of '
|
||||
'32 takes place. Many models support only the height chosen during training, which is '
|
||||
'used automatically if this parameter is not set.'
|
||||
)
|
||||
parser.add_argument('--square',
|
||||
action='store_true',
|
||||
help='Option to resize images to a square resolution by changing their widths when images are '
|
||||
'fed into the encoder during inference. If this parameter is not set, the aspect ratio of '
|
||||
'images is tried to be preserved if supported by the model.'
|
||||
)
|
||||
parser.add_argument('--grayscale',
|
||||
action='store_true',
|
||||
help='Use a grayscale colormap instead of the inferno one. Although the inferno colormap, '
|
||||
'which is used by default, is better for visibility, it does not allow storing 16-bit '
|
||||
'depth values in PNGs but only 8-bit ones due to the precision limitation of this '
|
||||
'colormap.'
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
|
||||
if args.model_weights is None:
|
||||
args.model_weights = default_models[args.model_type]
|
||||
|
||||
# set torch options
|
||||
torch.backends.cudnn.enabled = True
|
||||
torch.backends.cudnn.benchmark = True
|
||||
|
||||
# compute depth maps
|
||||
run(args.input_path, args.output_path, args.model_weights, args.model_type, args.optimize, args.side, args.height,
|
||||
args.square, args.grayscale)
|
||||
@@ -0,0 +1,147 @@
|
||||
## Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-shot Cross-dataset Transfer
|
||||
|
||||
### TensorFlow inference using `.pb` and `.onnx` models
|
||||
|
||||
1. [Run inference on TensorFlow-model by using TensorFlow](#run-inference-on-tensorflow-model-by-using-tensorFlow)
|
||||
|
||||
2. [Run inference on ONNX-model by using TensorFlow](#run-inference-on-onnx-model-by-using-tensorflow)
|
||||
|
||||
3. [Make ONNX model from downloaded Pytorch model file](#make-onnx-model-from-downloaded-pytorch-model-file)
|
||||
|
||||
|
||||
### Run inference on TensorFlow-model by using TensorFlow
|
||||
|
||||
1) Download the model weights [model-f6b98070.pb](https://github.com/isl-org/MiDaS/releases/download/v2_1/model-f6b98070.pb)
|
||||
and [model-small.pb](https://github.com/isl-org/MiDaS/releases/download/v2_1/model-small.pb) and place the
|
||||
file in the `/tf/` folder.
|
||||
|
||||
2) Set up dependencies:
|
||||
|
||||
```shell
|
||||
# install OpenCV
|
||||
pip install --upgrade pip
|
||||
pip install opencv-python
|
||||
|
||||
# install TensorFlow
|
||||
pip install -I grpcio tensorflow==2.3.0 tensorflow-addons==0.11.2 numpy==1.18.0
|
||||
```
|
||||
|
||||
#### Usage
|
||||
|
||||
1) Place one or more input images in the folder `tf/input`.
|
||||
|
||||
2) Run the model:
|
||||
|
||||
```shell
|
||||
python tf/run_pb.py
|
||||
```
|
||||
|
||||
Or run the small model:
|
||||
|
||||
```shell
|
||||
python tf/run_pb.py --model_weights model-small.pb --model_type small
|
||||
```
|
||||
|
||||
3) The resulting inverse depth maps are written to the `tf/output` folder.
|
||||
|
||||
|
||||
### Run inference on ONNX-model by using ONNX-Runtime
|
||||
|
||||
1) Download the model weights [model-f6b98070.onnx](https://github.com/isl-org/MiDaS/releases/download/v2_1/model-f6b98070.onnx)
|
||||
and [model-small.onnx](https://github.com/isl-org/MiDaS/releases/download/v2_1/model-small.onnx) and place the
|
||||
file in the `/tf/` folder.
|
||||
|
||||
2) Set up dependencies:
|
||||
|
||||
```shell
|
||||
# install OpenCV
|
||||
pip install --upgrade pip
|
||||
pip install opencv-python
|
||||
|
||||
# install ONNX
|
||||
pip install onnx==1.7.0
|
||||
|
||||
# install ONNX Runtime
|
||||
pip install onnxruntime==1.5.2
|
||||
```
|
||||
|
||||
#### Usage
|
||||
|
||||
1) Place one or more input images in the folder `tf/input`.
|
||||
|
||||
2) Run the model:
|
||||
|
||||
```shell
|
||||
python tf/run_onnx.py
|
||||
```
|
||||
|
||||
Or run the small model:
|
||||
|
||||
```shell
|
||||
python tf/run_onnx.py --model_weights model-small.onnx --model_type small
|
||||
```
|
||||
|
||||
3) The resulting inverse depth maps are written to the `tf/output` folder.
|
||||
|
||||
|
||||
|
||||
### Make ONNX model from downloaded Pytorch model file
|
||||
|
||||
1) Download the model weights [model-f6b98070.pt](https://github.com/isl-org/MiDaS/releases/download/v2_1/model-f6b98070.pt) and place the
|
||||
file in the root folder.
|
||||
|
||||
2) Set up dependencies:
|
||||
|
||||
```shell
|
||||
# install OpenCV
|
||||
pip install --upgrade pip
|
||||
pip install opencv-python
|
||||
|
||||
# install PyTorch TorchVision
|
||||
pip install -I torch==1.7.0 torchvision==0.8.0
|
||||
|
||||
# install TensorFlow
|
||||
pip install -I grpcio tensorflow==2.3.0 tensorflow-addons==0.11.2 numpy==1.18.0
|
||||
|
||||
# install ONNX
|
||||
pip install onnx==1.7.0
|
||||
|
||||
# install ONNX-TensorFlow
|
||||
git clone https://github.com/onnx/onnx-tensorflow.git
|
||||
cd onnx-tensorflow
|
||||
git checkout 095b51b88e35c4001d70f15f80f31014b592b81e
|
||||
pip install -e .
|
||||
```
|
||||
|
||||
#### Usage
|
||||
|
||||
1) Run the converter:
|
||||
|
||||
```shell
|
||||
python tf/make_onnx_model.py
|
||||
```
|
||||
|
||||
2) The resulting `model-f6b98070.onnx` file is written to the `/tf/` folder.
|
||||
|
||||
|
||||
### Requirements
|
||||
|
||||
The code was tested with Python 3.6.9, PyTorch 1.5.1, TensorFlow 2.2.0, TensorFlow-addons 0.8.3, ONNX 1.7.0, ONNX-TensorFlow (GitHub-master-17.07.2020) and OpenCV 4.3.0.
|
||||
|
||||
### Citation
|
||||
|
||||
Please cite our paper if you use this code or any of the models:
|
||||
```
|
||||
@article{Ranftl2019,
|
||||
author = {Ren\'{e} Ranftl and Katrin Lasinger and David Hafner and Konrad Schindler and Vladlen Koltun},
|
||||
title = {Towards Robust Monocular Depth Estimation: Mixing Datasets for Zero-shot Cross-dataset Transfer},
|
||||
journal = {IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI)},
|
||||
year = {2020},
|
||||
}
|
||||
```
|
||||
|
||||
### License
|
||||
|
||||
MIT License
|
||||
|
||||
|
||||
@@ -0,0 +1,113 @@
|
||||
"""Compute depth maps for images in the input folder.
|
||||
"""
|
||||
import fileinput
|
||||
import glob
|
||||
import ntpath
|
||||
import os
|
||||
import sys
|
||||
from shutil import copyfile
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import torch
|
||||
import utils
|
||||
from torchvision import transforms
|
||||
from torchvision.transforms import Compose, Normalize
|
||||
|
||||
sys.path.append(os.getcwd() + '/..')
|
||||
|
||||
def modify_file():
|
||||
modify_filename = '../midas/blocks.py'
|
||||
copyfile(modify_filename, modify_filename+'.bak')
|
||||
|
||||
with open(modify_filename, 'r') as file :
|
||||
filedata = file.read()
|
||||
|
||||
filedata = filedata.replace('align_corners=True', 'align_corners=False')
|
||||
filedata = filedata.replace('import torch.nn as nn', 'import torch.nn as nn\nimport torchvision.models as models')
|
||||
filedata = filedata.replace('torch.hub.load("facebookresearch/WSL-Images", "resnext101_32x8d_wsl")', 'models.resnext101_32x8d()')
|
||||
|
||||
with open(modify_filename, 'w') as file:
|
||||
file.write(filedata)
|
||||
|
||||
def restore_file():
|
||||
modify_filename = '../midas/blocks.py'
|
||||
copyfile(modify_filename+'.bak', modify_filename)
|
||||
|
||||
modify_file()
|
||||
|
||||
from midas.midas_net import MidasNet
|
||||
from midas.transforms import NormalizeImage, PrepareForNet, Resize
|
||||
|
||||
restore_file()
|
||||
|
||||
|
||||
class MidasNet_preprocessing(MidasNet):
|
||||
"""Network for monocular depth estimation.
|
||||
"""
|
||||
def forward(self, x):
|
||||
"""Forward pass.
|
||||
|
||||
Args:
|
||||
x (tensor): input data (image)
|
||||
|
||||
Returns:
|
||||
tensor: depth
|
||||
"""
|
||||
|
||||
mean = torch.tensor([0.485, 0.456, 0.406])
|
||||
std = torch.tensor([0.229, 0.224, 0.225])
|
||||
x.sub_(mean[None, :, None, None]).div_(std[None, :, None, None])
|
||||
|
||||
return MidasNet.forward(self, x)
|
||||
|
||||
|
||||
def run(model_path):
|
||||
"""Run MonoDepthNN to compute depth maps.
|
||||
|
||||
Args:
|
||||
model_path (str): path to saved model
|
||||
"""
|
||||
print("initialize")
|
||||
|
||||
# select device
|
||||
|
||||
# load network
|
||||
#model = MidasNet(model_path, non_negative=True)
|
||||
model = MidasNet_preprocessing(model_path, non_negative=True)
|
||||
|
||||
model.eval()
|
||||
|
||||
print("start processing")
|
||||
|
||||
# input
|
||||
img_input = np.zeros((3, 384, 384), np.float32)
|
||||
|
||||
# compute
|
||||
with torch.no_grad():
|
||||
sample = torch.from_numpy(img_input).unsqueeze(0)
|
||||
prediction = model.forward(sample)
|
||||
prediction = (
|
||||
torch.nn.functional.interpolate(
|
||||
prediction.unsqueeze(1),
|
||||
size=img_input.shape[:2],
|
||||
mode="bicubic",
|
||||
align_corners=False,
|
||||
)
|
||||
.squeeze()
|
||||
.cpu()
|
||||
.numpy()
|
||||
)
|
||||
|
||||
torch.onnx.export(model, sample, ntpath.basename(model_path).rsplit('.', 1)[0]+'.onnx', opset_version=9)
|
||||
|
||||
print("finished")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
# set paths
|
||||
# MODEL_PATH = "model.pt"
|
||||
MODEL_PATH = "../model-f6b98070.pt"
|
||||
|
||||
# compute depth maps
|
||||
run(MODEL_PATH)
|
||||
@@ -0,0 +1,118 @@
|
||||
"""Compute depth maps for images in the input folder.
|
||||
"""
|
||||
import argparse
|
||||
import glob
|
||||
import os
|
||||
import sys
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
import onnx
|
||||
import onnxruntime as rt
|
||||
import utils
|
||||
from transforms import NormalizeImage, PrepareForNet, Resize
|
||||
|
||||
|
||||
def run(input_path, output_path, model_path, model_type="large"):
|
||||
"""Run MonoDepthNN to compute depth maps.
|
||||
|
||||
Args:
|
||||
input_path (str): path to input folder
|
||||
output_path (str): path to output folder
|
||||
model_path (str): path to saved model
|
||||
"""
|
||||
print("initialize")
|
||||
|
||||
# select device
|
||||
device = "CUDA:0"
|
||||
#device = "CPU"
|
||||
print("device: %s" % device)
|
||||
|
||||
# network resolution
|
||||
if model_type == "large":
|
||||
net_w, net_h = 384, 384
|
||||
elif model_type == "small":
|
||||
net_w, net_h = 256, 256
|
||||
else:
|
||||
print(f"model_type '{model_type}' not implemented, use: --model_type large")
|
||||
assert False
|
||||
|
||||
# load network
|
||||
print("loading model...")
|
||||
model = rt.InferenceSession(model_path)
|
||||
input_name = model.get_inputs()[0].name
|
||||
output_name = model.get_outputs()[0].name
|
||||
|
||||
resize_image = Resize(
|
||||
net_w,
|
||||
net_h,
|
||||
resize_target=None,
|
||||
keep_aspect_ratio=False,
|
||||
ensure_multiple_of=32,
|
||||
resize_method="upper_bound",
|
||||
image_interpolation_method=cv2.INTER_CUBIC,
|
||||
)
|
||||
|
||||
def compose2(f1, f2):
|
||||
return lambda x: f2(f1(x))
|
||||
|
||||
transform = compose2(resize_image, PrepareForNet())
|
||||
|
||||
# get input
|
||||
img_names = glob.glob(os.path.join(input_path, "*"))
|
||||
num_images = len(img_names)
|
||||
|
||||
# create output folder
|
||||
os.makedirs(output_path, exist_ok=True)
|
||||
|
||||
print("start processing")
|
||||
|
||||
for ind, img_name in enumerate(img_names):
|
||||
|
||||
print(" processing {} ({}/{})".format(img_name, ind + 1, num_images))
|
||||
|
||||
# input
|
||||
img = utils.read_image(img_name)
|
||||
img_input = transform({"image": img})["image"]
|
||||
|
||||
# compute
|
||||
output = model.run([output_name], {input_name: img_input.reshape(1, 3, net_h, net_w).astype(np.float32)})[0]
|
||||
prediction = np.array(output).reshape(net_h, net_w)
|
||||
prediction = cv2.resize(prediction, (img.shape[1], img.shape[0]), interpolation=cv2.INTER_CUBIC)
|
||||
|
||||
# output
|
||||
filename = os.path.join(
|
||||
output_path, os.path.splitext(os.path.basename(img_name))[0]
|
||||
)
|
||||
utils.write_depth(filename, prediction, bits=2)
|
||||
|
||||
print("finished")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
|
||||
parser.add_argument('-i', '--input_path',
|
||||
default='input',
|
||||
help='folder with input images'
|
||||
)
|
||||
|
||||
parser.add_argument('-o', '--output_path',
|
||||
default='output',
|
||||
help='folder for output images'
|
||||
)
|
||||
|
||||
parser.add_argument('-m', '--model_weights',
|
||||
default='model-f6b98070.onnx',
|
||||
help='path to the trained weights of model'
|
||||
)
|
||||
|
||||
parser.add_argument('-t', '--model_type',
|
||||
default='large',
|
||||
help='model type: large or small'
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
# compute depth maps
|
||||
run(args.input_path, args.output_path, args.model_weights, args.model_type)
|
||||
@@ -0,0 +1,135 @@
|
||||
"""Compute depth maps for images in the input folder.
|
||||
"""
|
||||
import argparse
|
||||
import glob
|
||||
import os
|
||||
|
||||
import cv2
|
||||
import tensorflow as tf
|
||||
import utils
|
||||
from transforms import NormalizeImage, PrepareForNet, Resize
|
||||
|
||||
|
||||
def run(input_path, output_path, model_path, model_type="large"):
|
||||
"""Run MonoDepthNN to compute depth maps.
|
||||
|
||||
Args:
|
||||
input_path (str): path to input folder
|
||||
output_path (str): path to output folder
|
||||
model_path (str): path to saved model
|
||||
"""
|
||||
print("initialize")
|
||||
|
||||
# the runtime initialization will not allocate all memory on the device to avoid out of GPU memory
|
||||
gpus = tf.config.experimental.list_physical_devices('GPU')
|
||||
if gpus:
|
||||
try:
|
||||
for gpu in gpus:
|
||||
#tf.config.experimental.set_memory_growth(gpu, True)
|
||||
tf.config.experimental.set_virtual_device_configuration(gpu,
|
||||
[tf.config.experimental.VirtualDeviceConfiguration(memory_limit=4000)])
|
||||
except RuntimeError as e:
|
||||
print(e)
|
||||
|
||||
# network resolution
|
||||
if model_type == "large":
|
||||
net_w, net_h = 384, 384
|
||||
elif model_type == "small":
|
||||
net_w, net_h = 256, 256
|
||||
else:
|
||||
print(f"model_type '{model_type}' not implemented, use: --model_type large")
|
||||
assert False
|
||||
|
||||
# load network
|
||||
graph_def = tf.compat.v1.GraphDef()
|
||||
with tf.io.gfile.GFile(model_path, 'rb') as f:
|
||||
graph_def.ParseFromString(f.read())
|
||||
tf.import_graph_def(graph_def, name='')
|
||||
|
||||
|
||||
model_operations = tf.compat.v1.get_default_graph().get_operations()
|
||||
input_node = '0:0'
|
||||
output_layer = model_operations[len(model_operations) - 1].name + ':0'
|
||||
print("Last layer name: ", output_layer)
|
||||
|
||||
resize_image = Resize(
|
||||
net_w,
|
||||
net_h,
|
||||
resize_target=None,
|
||||
keep_aspect_ratio=False,
|
||||
ensure_multiple_of=32,
|
||||
resize_method="upper_bound",
|
||||
image_interpolation_method=cv2.INTER_CUBIC,
|
||||
)
|
||||
|
||||
def compose2(f1, f2):
|
||||
return lambda x: f2(f1(x))
|
||||
|
||||
transform = compose2(resize_image, PrepareForNet())
|
||||
|
||||
# get input
|
||||
img_names = glob.glob(os.path.join(input_path, "*"))
|
||||
num_images = len(img_names)
|
||||
|
||||
# create output folder
|
||||
os.makedirs(output_path, exist_ok=True)
|
||||
|
||||
print("start processing")
|
||||
|
||||
with tf.compat.v1.Session() as sess:
|
||||
try:
|
||||
# load images
|
||||
for ind, img_name in enumerate(img_names):
|
||||
|
||||
print(" processing {} ({}/{})".format(img_name, ind + 1, num_images))
|
||||
|
||||
# input
|
||||
img = utils.read_image(img_name)
|
||||
img_input = transform({"image": img})["image"]
|
||||
|
||||
# compute
|
||||
prob_tensor = sess.graph.get_tensor_by_name(output_layer)
|
||||
prediction, = sess.run(prob_tensor, {input_node: [img_input] })
|
||||
prediction = prediction.reshape(net_h, net_w)
|
||||
prediction = cv2.resize(prediction, (img.shape[1], img.shape[0]), interpolation=cv2.INTER_CUBIC)
|
||||
|
||||
# output
|
||||
filename = os.path.join(
|
||||
output_path, os.path.splitext(os.path.basename(img_name))[0]
|
||||
)
|
||||
utils.write_depth(filename, prediction, bits=2)
|
||||
|
||||
except KeyError:
|
||||
print ("Couldn't find input node: ' + input_node + ' or output layer: " + output_layer + ".")
|
||||
exit(-1)
|
||||
|
||||
print("finished")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
parser = argparse.ArgumentParser()
|
||||
|
||||
parser.add_argument('-i', '--input_path',
|
||||
default='input',
|
||||
help='folder with input images'
|
||||
)
|
||||
|
||||
parser.add_argument('-o', '--output_path',
|
||||
default='output',
|
||||
help='folder for output images'
|
||||
)
|
||||
|
||||
parser.add_argument('-m', '--model_weights',
|
||||
default='model-f6b98070.pb',
|
||||
help='path to the trained weights of model'
|
||||
)
|
||||
|
||||
parser.add_argument('-t', '--model_type',
|
||||
default='large',
|
||||
help='model type: large or small'
|
||||
)
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
# compute depth maps
|
||||
run(args.input_path, args.output_path, args.model_weights, args.model_type)
|
||||