Compare commits
15
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 gokayfem |
4c200c4dda | ||
|
gokayfem
|
58fd4823b9 | ||
|
gokayfem
|
2efd3631b8 | ||
|
gokayfem
|
bcb756d973 | ||
|
gokayfem
|
37317a8478 | ||
|
gokayfem
|
460b27a1b5 | ||
|
gokayfem
|
1e04a56444 | ||
|
gokayfem
|
b89f6288bb | ||
|
Gökay Aydoğan
|
066b10fd60 | ||
|
Gökay Aydoğan
|
eabca719dd | ||
|
Gökay Aydoğan
|
8bd18dd52b | ||
|
mavibirdesmi
|
858ab8a13e | ||
|
Gökay Aydoğan
|
1ca496c1c8 | ||
|
Juggernaut
|
7174a2ac91 | ||
|
Juggernaut
|
77f70e4417 |
@@ -0,0 +1,60 @@
|
||||
name: CI
|
||||
|
||||
on:
|
||||
push:
|
||||
pull_request:
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
test:
|
||||
name: ${{ matrix.label }}
|
||||
runs-on: ${{ matrix.os }}
|
||||
timeout-minutes: 35
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
include:
|
||||
- label: Linux / Python 3.10
|
||||
os: ubuntu-latest
|
||||
python: "3.10"
|
||||
cpu_index: true
|
||||
- label: Linux / Python 3.13
|
||||
os: ubuntu-latest
|
||||
python: "3.13"
|
||||
cpu_index: true
|
||||
- label: Windows / Python 3.12
|
||||
os: windows-latest
|
||||
python: "3.12"
|
||||
cpu_index: true
|
||||
- label: macOS / Python 3.12
|
||||
os: macos-14
|
||||
python: "3.12"
|
||||
cpu_index: false
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
- uses: actions/setup-python@v7
|
||||
with:
|
||||
python-version: ${{ matrix.python }}
|
||||
cache: pip
|
||||
cache-dependency-path: requirements.txt
|
||||
- name: Install CPU PyTorch
|
||||
if: matrix.cpu_index == true
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install torch --index-url https://download.pytorch.org/whl/cpu
|
||||
- name: Install macOS PyTorch
|
||||
if: matrix.cpu_index == false
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install torch
|
||||
- name: Install ComfyUI and node dependencies
|
||||
run: |
|
||||
git clone --depth 1 https://github.com/Comfy-Org/ComfyUI.git ../ComfyUI
|
||||
python -m pip install pytest packaging
|
||||
python -m pip install -r ../ComfyUI/requirements.txt -r requirements.txt
|
||||
- name: Test
|
||||
run: python -m pytest -q
|
||||
- name: Compile
|
||||
run: python -m compileall -q .
|
||||
@@ -0,0 +1,171 @@
|
||||
name: Publish Comfy node fleet
|
||||
|
||||
on:
|
||||
workflow_dispatch:
|
||||
inputs:
|
||||
target:
|
||||
description: Node repository to check
|
||||
required: true
|
||||
default: all
|
||||
type: choice
|
||||
options:
|
||||
- all
|
||||
- vlm
|
||||
- depth
|
||||
- dream
|
||||
- texture
|
||||
schedule:
|
||||
- cron: "17 * * * *"
|
||||
push:
|
||||
branches:
|
||||
- main
|
||||
paths:
|
||||
- ".github/workflows/publish-fleet.yml"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
concurrency:
|
||||
group: comfy-registry-fleet
|
||||
cancel-in-progress: false
|
||||
|
||||
jobs:
|
||||
publish:
|
||||
name: Check ${{ matrix.target }}
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
include:
|
||||
- target: vlm
|
||||
repository: gokayfem/ComfyUI_VLM_nodes
|
||||
node_id: comfyui_vlm_nodes
|
||||
- target: depth
|
||||
repository: gokayfem/ComfyUI-Depth-Visualization
|
||||
node_id: comfyui-depth-visualization
|
||||
- target: dream
|
||||
repository: gokayfem/ComfyUI-Dream-Interpreter
|
||||
node_id: comfyui-dream-interpreter
|
||||
- target: texture
|
||||
repository: gokayfem/ComfyUI-Texture-Simple
|
||||
node_id: comfyui-texture-simple
|
||||
|
||||
steps:
|
||||
- name: Select target
|
||||
id: select
|
||||
env:
|
||||
REQUESTED_TARGET: ${{ inputs.target || 'all' }}
|
||||
MATRIX_TARGET: ${{ matrix.target }}
|
||||
run: |
|
||||
if [[ "$REQUESTED_TARGET" == "all" || "$REQUESTED_TARGET" == "$MATRIX_TARGET" ]]; then
|
||||
echo "selected=true" >> "$GITHUB_OUTPUT"
|
||||
else
|
||||
echo "selected=false" >> "$GITHUB_OUTPUT"
|
||||
fi
|
||||
|
||||
- name: Check out node
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
uses: actions/checkout@v7
|
||||
with:
|
||||
repository: ${{ matrix.repository }}
|
||||
ref: main
|
||||
path: node
|
||||
persist-credentials: false
|
||||
|
||||
- name: Set up Python
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
uses: actions/setup-python@v7
|
||||
with:
|
||||
python-version: "3.12"
|
||||
|
||||
- name: Read and verify release metadata
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
id: metadata
|
||||
working-directory: node
|
||||
env:
|
||||
EXPECTED_NODE_ID: ${{ matrix.node_id }}
|
||||
run: |
|
||||
python - <<'PY'
|
||||
import os
|
||||
import tomllib
|
||||
from pathlib import Path
|
||||
|
||||
metadata = tomllib.loads(Path("pyproject.toml").read_text(encoding="utf-8"))
|
||||
node_id = metadata["project"]["name"]
|
||||
version = metadata["project"]["version"]
|
||||
publisher = metadata["tool"]["comfy"]["PublisherId"]
|
||||
expected = os.environ["EXPECTED_NODE_ID"]
|
||||
|
||||
if node_id != expected:
|
||||
raise SystemExit(f"Expected node id {expected!r}, found {node_id!r}")
|
||||
if publisher != "gokayfem":
|
||||
raise SystemExit(f"Expected publisher 'gokayfem', found {publisher!r}")
|
||||
|
||||
with Path(os.environ["GITHUB_OUTPUT"]).open("a", encoding="utf-8") as output:
|
||||
print(f"node_id={node_id}", file=output)
|
||||
print(f"version={version}", file=output)
|
||||
PY
|
||||
|
||||
- name: Check Registry version
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
id: registry
|
||||
env:
|
||||
NODE_ID: ${{ steps.metadata.outputs.node_id }}
|
||||
VERSION: ${{ steps.metadata.outputs.version }}
|
||||
run: |
|
||||
python - <<'PY'
|
||||
import json
|
||||
import os
|
||||
import urllib.parse
|
||||
import urllib.request
|
||||
from pathlib import Path
|
||||
|
||||
node_id = urllib.parse.quote(os.environ["NODE_ID"], safe="")
|
||||
url = f"https://api.comfy.org/nodes/{node_id}/versions"
|
||||
request = urllib.request.Request(
|
||||
url,
|
||||
headers={"Accept": "application/json", "User-Agent": "comfy-node-fleet-publisher"},
|
||||
)
|
||||
with urllib.request.urlopen(request, timeout=30) as response:
|
||||
versions = json.load(response)
|
||||
|
||||
wanted = os.environ["VERSION"]
|
||||
exists = any(item.get("version") == wanted for item in versions)
|
||||
with Path(os.environ["GITHUB_OUTPUT"]).open("a", encoding="utf-8") as output:
|
||||
print(f"exists={'true' if exists else 'false'}", file=output)
|
||||
PY
|
||||
|
||||
- name: Require publisher credential
|
||||
if: steps.select.outputs.selected == 'true' && steps.registry.outputs.exists != 'true'
|
||||
env:
|
||||
REGISTRY_ACCESS_TOKEN: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
run: |
|
||||
if [[ -z "$REGISTRY_ACCESS_TOKEN" ]]; then
|
||||
echo "::error title=Missing registry token::Add the publisher API key as the REGISTRY_ACCESS_TOKEN repository secret."
|
||||
exit 1
|
||||
fi
|
||||
|
||||
- name: Install pinned publisher
|
||||
if: steps.select.outputs.selected == 'true' && steps.registry.outputs.exists != 'true'
|
||||
run: python -m pip install --disable-pip-version-check --no-input "comfy-cli==1.13.0"
|
||||
|
||||
- name: Publish missing version
|
||||
if: steps.select.outputs.selected == 'true' && steps.registry.outputs.exists != 'true'
|
||||
working-directory: node
|
||||
env:
|
||||
REGISTRY_ACCESS_TOKEN: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
run: comfy --skip-prompt --no-enable-telemetry node publish --token "$REGISTRY_ACCESS_TOKEN"
|
||||
|
||||
- name: Record result
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
env:
|
||||
NODE_ID: ${{ steps.metadata.outputs.node_id }}
|
||||
VERSION: ${{ steps.metadata.outputs.version }}
|
||||
ALREADY_PUBLISHED: ${{ steps.registry.outputs.exists }}
|
||||
run: |
|
||||
if [[ "$ALREADY_PUBLISHED" == "true" ]]; then
|
||||
echo "### $NODE_ID $VERSION already published" >> "$GITHUB_STEP_SUMMARY"
|
||||
else
|
||||
echo "### Published $NODE_ID $VERSION" >> "$GITHUB_STEP_SUMMARY"
|
||||
fi
|
||||
@@ -6,16 +6,109 @@ on:
|
||||
- main
|
||||
paths:
|
||||
- "pyproject.toml"
|
||||
- ".github/workflows/publish.yml"
|
||||
|
||||
concurrency:
|
||||
group: comfy-registry-${{ github.repository }}
|
||||
cancel-in-progress: false
|
||||
|
||||
env:
|
||||
COMFY_CLI_VERSION: "1.13.0"
|
||||
|
||||
jobs:
|
||||
publish-node:
|
||||
name: Publish Custom Node to registry
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
permissions:
|
||||
contents: read
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v4
|
||||
- name: Publish Custom Node
|
||||
uses: Comfy-Org/publish-node-action@main
|
||||
uses: actions/checkout@v7
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@v7
|
||||
with:
|
||||
## Add your own personal access token to your Github Repository secrets and reference it here.
|
||||
personal_access_token: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
python-version: "3.12"
|
||||
- name: Read release metadata
|
||||
id: metadata
|
||||
run: |
|
||||
python - <<'PY'
|
||||
import os
|
||||
import tomllib
|
||||
from pathlib import Path
|
||||
|
||||
metadata = tomllib.loads(Path("pyproject.toml").read_text(encoding="utf-8"))
|
||||
node_id = metadata["project"]["name"]
|
||||
version = metadata["project"]["version"]
|
||||
publisher = metadata["tool"]["comfy"]["PublisherId"]
|
||||
if publisher != "gokayfem":
|
||||
raise SystemExit(f"Expected publisher 'gokayfem', found {publisher!r}")
|
||||
|
||||
with Path(os.environ["GITHUB_OUTPUT"]).open("a", encoding="utf-8") as output:
|
||||
print(f"node_id={node_id}", file=output)
|
||||
print(f"version={version}", file=output)
|
||||
PY
|
||||
- name: Check Registry version
|
||||
id: registry
|
||||
env:
|
||||
NODE_ID: ${{ steps.metadata.outputs.node_id }}
|
||||
VERSION: ${{ steps.metadata.outputs.version }}
|
||||
run: |
|
||||
python - <<'PY'
|
||||
import json
|
||||
import os
|
||||
import urllib.parse
|
||||
import urllib.request
|
||||
from pathlib import Path
|
||||
|
||||
node_id = urllib.parse.quote(os.environ["NODE_ID"], safe="")
|
||||
request = urllib.request.Request(
|
||||
f"https://api.comfy.org/nodes/{node_id}/versions",
|
||||
headers={"Accept": "application/json", "User-Agent": "comfy-node-publisher"},
|
||||
)
|
||||
with urllib.request.urlopen(request, timeout=30) as response:
|
||||
versions = json.load(response)
|
||||
|
||||
exists = any(item.get("version") == os.environ["VERSION"] for item in versions)
|
||||
with Path(os.environ["GITHUB_OUTPUT"]).open("a", encoding="utf-8") as output:
|
||||
print(f"exists={'true' if exists else 'false'}", file=output)
|
||||
PY
|
||||
- name: Check publisher credential
|
||||
if: steps.registry.outputs.exists != 'true'
|
||||
id: credentials
|
||||
env:
|
||||
REGISTRY_ACCESS_TOKEN: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
run: |
|
||||
if [[ -n "$REGISTRY_ACCESS_TOKEN" ]]; then
|
||||
echo "available=true" >> "$GITHUB_OUTPUT"
|
||||
else
|
||||
echo "available=false" >> "$GITHUB_OUTPUT"
|
||||
echo "::notice title=Central publisher enabled::The secure fleet publisher will publish this release within one hour."
|
||||
fi
|
||||
- name: Install pinned Comfy CLI
|
||||
if: steps.registry.outputs.exists != 'true' && steps.credentials.outputs.available == 'true'
|
||||
shell: bash
|
||||
run: python -m pip install --disable-pip-version-check "comfy-cli==${COMFY_CLI_VERSION}"
|
||||
- name: Publish Custom Node
|
||||
if: steps.registry.outputs.exists != 'true' && steps.credentials.outputs.available == 'true'
|
||||
id: publish
|
||||
continue-on-error: true
|
||||
shell: bash
|
||||
env:
|
||||
REGISTRY_ACCESS_TOKEN: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
run: comfy --skip-prompt --no-enable-telemetry node publish --token "$REGISTRY_ACCESS_TOKEN"
|
||||
- name: Record publication result
|
||||
env:
|
||||
NODE_ID: ${{ steps.metadata.outputs.node_id }}
|
||||
VERSION: ${{ steps.metadata.outputs.version }}
|
||||
ALREADY_PUBLISHED: ${{ steps.registry.outputs.exists }}
|
||||
PUBLISH_OUTCOME: ${{ steps.publish.outcome }}
|
||||
run: |
|
||||
if [[ "$ALREADY_PUBLISHED" == "true" ]]; then
|
||||
echo "### $NODE_ID $VERSION already published" >> "$GITHUB_STEP_SUMMARY"
|
||||
elif [[ "$PUBLISH_OUTCOME" == "success" ]]; then
|
||||
echo "### Published $NODE_ID $VERSION" >> "$GITHUB_STEP_SUMMARY"
|
||||
else
|
||||
echo "::notice title=Central publishing handoff::The secure fleet publisher will retry this release within one hour."
|
||||
echo "### $NODE_ID $VERSION queued for the fleet publisher" >> "$GITHUB_STEP_SUMMARY"
|
||||
fi
|
||||
|
||||
@@ -0,0 +1,123 @@
|
||||
# Platform and accelerator compatibility
|
||||
|
||||
ComfyUI owns PyTorch. This node pack deliberately does not depend on `torch`,
|
||||
`torchvision`, or a vendor wheel, because installing a generic PyPI build can
|
||||
silently replace a working CUDA, ROCm, XPU, or Metal environment.
|
||||
|
||||
Install `requirements.txt` with the same Python executable that starts ComfyUI.
|
||||
The **VLM Runtime Diagnostics** node reports the environment seen by the pack
|
||||
without downloading a model.
|
||||
|
||||
## Support matrix
|
||||
|
||||
| Platform | Managed Transformers | bitsandbytes 4/8-bit | GGUF acceleration |
|
||||
| --- | --- | --- | --- |
|
||||
| Linux + NVIDIA | CUDA, BF16/FP16 capability detected | Official wheel | CUDA or Vulkan |
|
||||
| Windows + NVIDIA | CUDA, BF16/FP16 capability detected | Official wheel | CUDA or Vulkan |
|
||||
| Linux + AMD | ROCm through PyTorch's `cuda` API | Official ROCm wheel for listed GPU architectures | ROCm/HIP or Vulkan |
|
||||
| Windows + AMD | Current ComfyUI/AMD ROCm PyTorch builds | Official ROCm Windows wheel for listed GPU architectures | HIP Radeon or Vulkan |
|
||||
| Apple Silicon macOS | MPS, BF16 on supported macOS/PyTorch; FP16 fallback | Official arm64 wheel | Metal |
|
||||
| Intel GPU | XPU with BF16 capability detection | Official XPU/CPU wheel | SYCL or Vulkan |
|
||||
| CPU | FP32 | Official wheels on supported architectures | OpenBLAS or default CPU |
|
||||
| Intel macOS | CPU/legacy MPS environment as provided by ComfyUI | No official bitsandbytes wheel; dependency is skipped | CPU build |
|
||||
|
||||
The default **ComfyUI managed** mode is the portable path. Quantization is an
|
||||
optional optimization, not an import requirement. DirectML/private-use devices
|
||||
receive a safe FP32 fallback, but are best-effort because current ComfyUI itself
|
||||
does not treat DirectML as a primary performance backend.
|
||||
|
||||
## Dependency behavior
|
||||
|
||||
- Python 3.10 through 3.13 is covered by CI.
|
||||
- `transformers>=5.4,<6` and `huggingface-hub>=1.5,<2` are paired intentionally;
|
||||
Transformers 5.4 requires Hub 1.5 or newer.
|
||||
- `bitsandbytes>=0.50` is the first dependency floor used here for the current
|
||||
multi-backend releases. Environment markers prevent an unsupported wheel
|
||||
from blocking the whole node pack.
|
||||
- `requirements-quantization.txt` is available for an explicit quantization
|
||||
install or source-build environment.
|
||||
- Model downloads, imports, and package compilation never occur during node
|
||||
discovery.
|
||||
|
||||
Install manually:
|
||||
|
||||
```bash
|
||||
python -m pip install -r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements.txt
|
||||
```
|
||||
|
||||
If quantization was skipped but the machine has a supported custom build:
|
||||
|
||||
```bash
|
||||
python -m pip install -r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements-quantization.txt
|
||||
```
|
||||
|
||||
## llama.cpp / GGUF
|
||||
|
||||
`llama-cpp-python` must be compiled or selected for the actual backend. Its
|
||||
official project currently publishes backend indexes and documents source
|
||||
build flags:
|
||||
|
||||
```bash
|
||||
# NVIDIA; replace cu124 with the CUDA index matching the environment.
|
||||
python -m pip install llama-cpp-python \
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/cu124
|
||||
|
||||
# Apple Metal
|
||||
python -m pip install llama-cpp-python \
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/metal
|
||||
|
||||
# Linux ROCm
|
||||
python -m pip install llama-cpp-python \
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/rocm72
|
||||
|
||||
# Linux or Windows Vulkan
|
||||
python -m pip install llama-cpp-python \
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/vulkan
|
||||
```
|
||||
|
||||
The official Windows HIP Radeon index is:
|
||||
|
||||
```powershell
|
||||
python -m pip install llama-cpp-python `
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/hip-radeon
|
||||
```
|
||||
|
||||
Source builds use `GGML_CUDA=on`, `GGML_METAL=on`, `GGML_HIP=on`,
|
||||
`GGML_VULKAN=on`, or `GGML_SYCL=on` through `CMAKE_ARGS`. Use an arm64 Python
|
||||
on Apple Silicon; an x86 Python builds the wrong architecture and is
|
||||
dramatically slower.
|
||||
|
||||
Authoritative installation references:
|
||||
|
||||
- [ComfyUI installation and hardware backends](https://github.com/Comfy-Org/ComfyUI)
|
||||
- [bitsandbytes installation and supported hardware](https://huggingface.co/docs/bitsandbytes/installation)
|
||||
- [llama-cpp-python supported backends](https://github.com/abetlen/llama-cpp-python#supported-backends)
|
||||
|
||||
## Attention and offloading
|
||||
|
||||
- **Auto (SDPA)** lets PyTorch choose its maintained kernel and is the default
|
||||
on every backend.
|
||||
- **Flash Attention 2** is preflighted for CUDA/ROCm only. A compatible
|
||||
`flash-attn` build is still required.
|
||||
- ComfyUI-managed models participate in its normal model patcher lifecycle.
|
||||
- External bitsandbytes and llama.cpp allocations ask ComfyUI to free space
|
||||
first, then release only their owned model on unload.
|
||||
- Automatic CPU/disk device mapping is used for large CUDA/ROCm/XPU models.
|
||||
MPS unified memory and CPU use an explicit active-device map.
|
||||
- AudioLDM2 uses FP16 on capable accelerators, FP32 on CPU, CUDA-API CPU
|
||||
offload for NVIDIA/ROCm, and a portable CPU random generator on MPS.
|
||||
|
||||
## What CI proves
|
||||
|
||||
Every push installs current ComfyUI plus this complete `requirements.txt` and
|
||||
runs imports, schemas, runtime contracts, tests, and byte-compilation on:
|
||||
|
||||
- Ubuntu, Python 3.10
|
||||
- Ubuntu, Python 3.13
|
||||
- Windows, Python 3.12
|
||||
- macOS, Python 3.12
|
||||
|
||||
Hosted runners do not contain production NVIDIA, AMD, or Intel GPUs. CI
|
||||
therefore tests backend selection and dtype/device-map contracts, while real
|
||||
GPU model smoke tests remain explicit hardware validation. It does not claim
|
||||
that a CPU simulation executed a vendor kernel.
|
||||
@@ -0,0 +1,49 @@
|
||||
# Model validation
|
||||
|
||||
Validated on 2026-07-28 with ComfyUI 0.28.0, Python 3.12, Transformers 5.14.1,
|
||||
PyTorch 2.13.0+cu126, and an RTX 3090 24 GB. All models and caches were stored
|
||||
on the D drive and executed through WSL.
|
||||
|
||||
## Real-weight passes
|
||||
|
||||
| Family | Representative result | Peak CUDA |
|
||||
| --- | --- | ---: |
|
||||
| Qwen 3.5 | 0.8B BF16 image/video; 0.8B NF4; 2B, 4B, and 9B images | 0.82–17.62 GiB |
|
||||
| Qwen 3 VL | 2B, 4B, and 8B images returned the correct red object | 3.99–16.37 GiB |
|
||||
| SmolVLM2 | 500M image/video and 2.2B video returned the correct object | 2.29–5.41 GiB |
|
||||
| LFM2.5 VL | 450M returned “red … rectangle” | 0.88 GiB |
|
||||
| InternVL 3.5 | 1B video returned “green rectangle” after the 448px patch-grid fix | 2.14 GiB |
|
||||
| Granite Vision 4.1 | 4B returned “solid red square” through native Transformers code | 7.61 GiB |
|
||||
| Florence-2 | Native converted base-FT returned and parsed a bright-red-square caption | 0.59 GiB |
|
||||
|
||||
One checkpoint covers sibling sizes that use the same architecture and loader.
|
||||
The node does not download every size simply to repeat the same integration
|
||||
test.
|
||||
|
||||
## ComfyUI API pass
|
||||
|
||||
ComfyUI started from the D-drive WSL installation with all four repaired custom
|
||||
node repositories enabled and no custom-node import failures. A real local API
|
||||
workflow (`EmptyImage` -> `ModernVLM` -> `ViewText`) ran the cached LFM2.5-VL
|
||||
450M checkpoint on a solid red input, returned `Red.`, and completed with
|
||||
`unload_after=true`. Prompt ID:
|
||||
`919f92cd-ecb2-487b-abf0-19f5e4d88229`.
|
||||
|
||||
## Catalog validation
|
||||
|
||||
Configuration and processor resolution passed for all 15 ungated entries in
|
||||
the small/fast catalog: Qwen 3.5 0.8B/2B/4B, Qwen 3 VL 2B/4B, Qwen 2.5 VL 3B,
|
||||
SmolVLM2 256M/500M/2.2B, LFM2.5 VL 450M/1.6B, InternVL 3.5 1B/2B, and Granite
|
||||
Vision 3.3 2B/4.1 4B. Gemma 3 4B is the sixteenth entry and correctly requires
|
||||
license acceptance plus `HF_TOKEN`.
|
||||
|
||||
## Not marked passed
|
||||
|
||||
- Qwen 3 VL 30B-A3B: weights are available locally, but inference validation
|
||||
was stopped at the user's request and will not be repeated.
|
||||
- Moondream2 2025-06-21: its pinned remote wrapper needed Transformers 5 loading
|
||||
metadata, but this Torch/CUDA stack produced NaN probabilities when sampling
|
||||
and immediate EOS with greedy decoding. The node defaults to the
|
||||
non-destructive greedy path and raises an actionable error on an empty result.
|
||||
- PaLI-Gemma and Gemma 3: gated checkpoints were not accessible without an
|
||||
accepted license and token.
|
||||
@@ -1,167 +1,145 @@
|
||||
<div align="center">
|
||||
<h1> 👁️ VLM Nodes</h1>
|
||||
<p align="center">
|
||||
<b> 🔽Examples below</b> •
|
||||
📙 <a href="https://github.com/gokayfem/Awesome-VLM-Architectures">Visit my other repo to learn more about Vision Language Models</a>
|
||||
</p>
|
||||
</div>
|
||||
<br/>
|
||||
# ComfyUI VLM Nodes
|
||||
|
||||
## Usage
|
||||
- For **Windows** and **Linux**
|
||||
Production-oriented vision-language, structured prompting, audio, and utility
|
||||
nodes for ComfyUI. Version 2.1 supports ComfyUI's selected NVIDIA CUDA, AMD
|
||||
ROCm, Apple Metal, Intel XPU, and CPU device without replacing its PyTorch
|
||||
build. It removes startup installers and global accelerator cache flushes,
|
||||
adds real image/video batches, and uses ComfyUI model residency and offloading.
|
||||
|
||||
## Modern model coverage
|
||||
|
||||
The **Modern VLM** node provides one stable interface for:
|
||||
|
||||
- Qwen 3.5 0.8B, 2B, 4B, 9B, 27B, and 35B-A3B
|
||||
- Qwen 3.6 27B
|
||||
- Qwen 3 VL 2B, 4B, 8B, and 30B-A3B Instruct
|
||||
- Qwen 2.5 VL 3B and 7B for existing workflows
|
||||
- Gemma 3 4B, 12B, and 27B IT
|
||||
- SmolVLM2 256M, 500M, and 2.2B video models
|
||||
- Liquid LFM2.5-VL 450M and 1.6B edge models
|
||||
- InternVL 3.5 1B and 2B standard Hugging Face checkpoints
|
||||
- Granite Vision 3.3 2B and 4.1 4B for documents, charts, and OCR
|
||||
- a compatible custom Hugging Face image-to-text repository
|
||||
|
||||
Sixteen curated sub-4B/low-VRAM choices are marked internally as the
|
||||
small-and-fast tier. The default is Qwen 3 VL 2B: it is much quicker to load
|
||||
than larger checkpoints while retaining broad image and video understanding.
|
||||
The catalog intentionally uses official model repositories and maintained
|
||||
Transformers interfaces rather than unverified community quantizations.
|
||||
Curated models use native Transformers implementations; remote repository code
|
||||
is enabled only when the explicit custom-model option requires it. Florence-2
|
||||
uses the Transformers-native converted checkpoints instead of Microsoft’s
|
||||
legacy repository code.
|
||||
|
||||
Specialized nodes remain available where a generic chat node would discard
|
||||
useful model capabilities:
|
||||
|
||||
- **Florence-2**: captioning, OCR, detection, region captioning, and referring
|
||||
expression segmentation, with structured JSON, mask, and overlay outputs.
|
||||
- **PaLI-Gemma**: caption/VQA plus the official 16-token VQ-VAE segmentation
|
||||
decoder; segmentation tokens are no longer misinterpreted as polygon points.
|
||||
- **Moondream2**: pinned query API with explicit decoding controls. Its current
|
||||
checkpoint is not marked passed on the tested Torch/Transformers stack; use a
|
||||
small Modern VLM preset for production.
|
||||
- **Qwen2-VL**: image batches and real video-frame batches.
|
||||
- **Molmo, Kosmos-2, UForm, MCLLaVA, JoyTag, and MiniCPM-V 2.6 GGUF**.
|
||||
- **llama.cpp LLaVA/GGUF**, structured prompt suggestions, OpenAI-compatible
|
||||
prompting, and AudioLDM2.
|
||||
|
||||
## Install
|
||||
|
||||
Install through ComfyUI Manager, or clone into `ComfyUI/custom_nodes` and run:
|
||||
|
||||
```bash
|
||||
python -m pip install -r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements.txt
|
||||
```
|
||||
cd custom_nodes
|
||||
git clone https://github.com/gokayfem/ComfyUI_VLM_nodes.git
|
||||
|
||||
Run that command with ComfyUI's Python. Do not install or replace `torch` from
|
||||
this repository: ComfyUI's own installer selects CUDA, ROCm, XPU, Metal, or CPU.
|
||||
Current official bitsandbytes wheels are installed automatically only on their
|
||||
supported OS/architecture combinations. Unsupported machines retain all
|
||||
non-quantized nodes.
|
||||
|
||||
GGUF nodes use optional `llama-cpp-python`. Install a wheel built for the
|
||||
desired CUDA, ROCm/HIP, Metal, Vulkan, SYCL, or CPU backend:
|
||||
|
||||
```bash
|
||||
python -m pip install -r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements-llama-cpp.txt
|
||||
```
|
||||
## Acknowledgements
|
||||
|
||||
- [JAGS](https://github.com/jags111)
|
||||
- [EnragedAntelope](https://github.com/EnragedAntelope)
|
||||
See [COMPATIBILITY.md](COMPATIBILITY.md) for the tested matrix and official
|
||||
backend-specific GGUF commands.
|
||||
|
||||
**If you get errors related to llama-cpp-python or if it is not using GPU.**
|
||||
**I recommend installing it with the right arguments provided in this link [llama-cpp-python](https://github.com/abetlen/llama-cpp-python?tab=readme-ov-file#installation)**
|
||||
Models are downloaded only when their node first executes and are stored below
|
||||
`ComfyUI/models/LLavacheckpoints`. Hugging Face downloads respect `HF_TOKEN`.
|
||||
Gemma 3 and PaLI-Gemma require accepting their model licenses on Hugging Face.
|
||||
|
||||
## VLM Nodes
|
||||
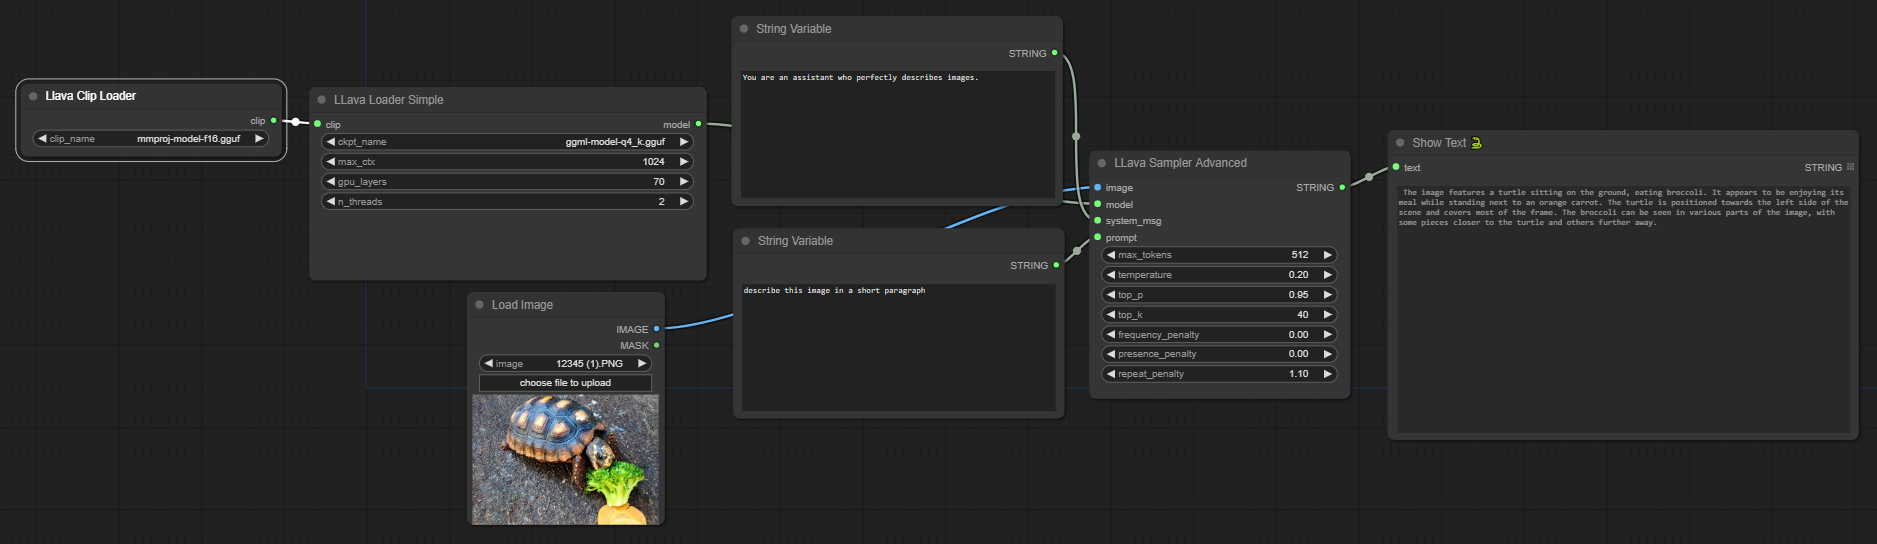
Utilizes ```llama-cpp-python``` for integration of LLaVa models. You can load and use any VLM with LLaVa models in GGUF format with this nodes.
|
||||
You need to download the model similar to ```ggml-model-q4_k.gguf``` and it's clip projector similar to ```mmproj-model-f16.gguf``` from this repositories (in the files and versions).
|
||||
```python=>3.9``` is necessary.
|
||||
Put all of the files inside ```models/LLavacheckpoints```
|
||||
Note that every **model's clip projector** is different!
|
||||
- [LlaVa 1.6 Mistral 7B](https://huggingface.co/cjpais/llava-1.6-mistral-7b-gguf/)
|
||||
- [Nous Hermes 2 Vision](https://huggingface.co/billborkowski/llava-NousResearch_Nous-Hermes-2-Vision-GGUF)
|
||||
- [LlaVa 1.5 7B](https://huggingface.co/mys/ggml_llava-v1.5-7b/)
|
||||
- [LlaVa 1.5 13B](https://huggingface.co/mys/ggml_llava-v1.5-13b)
|
||||
- [BakLLaVa](https://huggingface.co/mys/ggml_bakllava-1)
|
||||
etc..
|
||||
## GPU lifecycle
|
||||
|
||||
## Structured Output
|
||||
Getting structured outputs can be quite challenging through prompt engineering alone.
|
||||
I've added the Structured Output node to VLM Nodes.
|
||||
Now, you can obtain your answers reliably.
|
||||
You can extract entities, numbers, classify prompts with given classes, and generate one specific prompt. These are just a few examples.
|
||||
You can add additional descriptions to fields and choose the attributes you want it to return.
|
||||
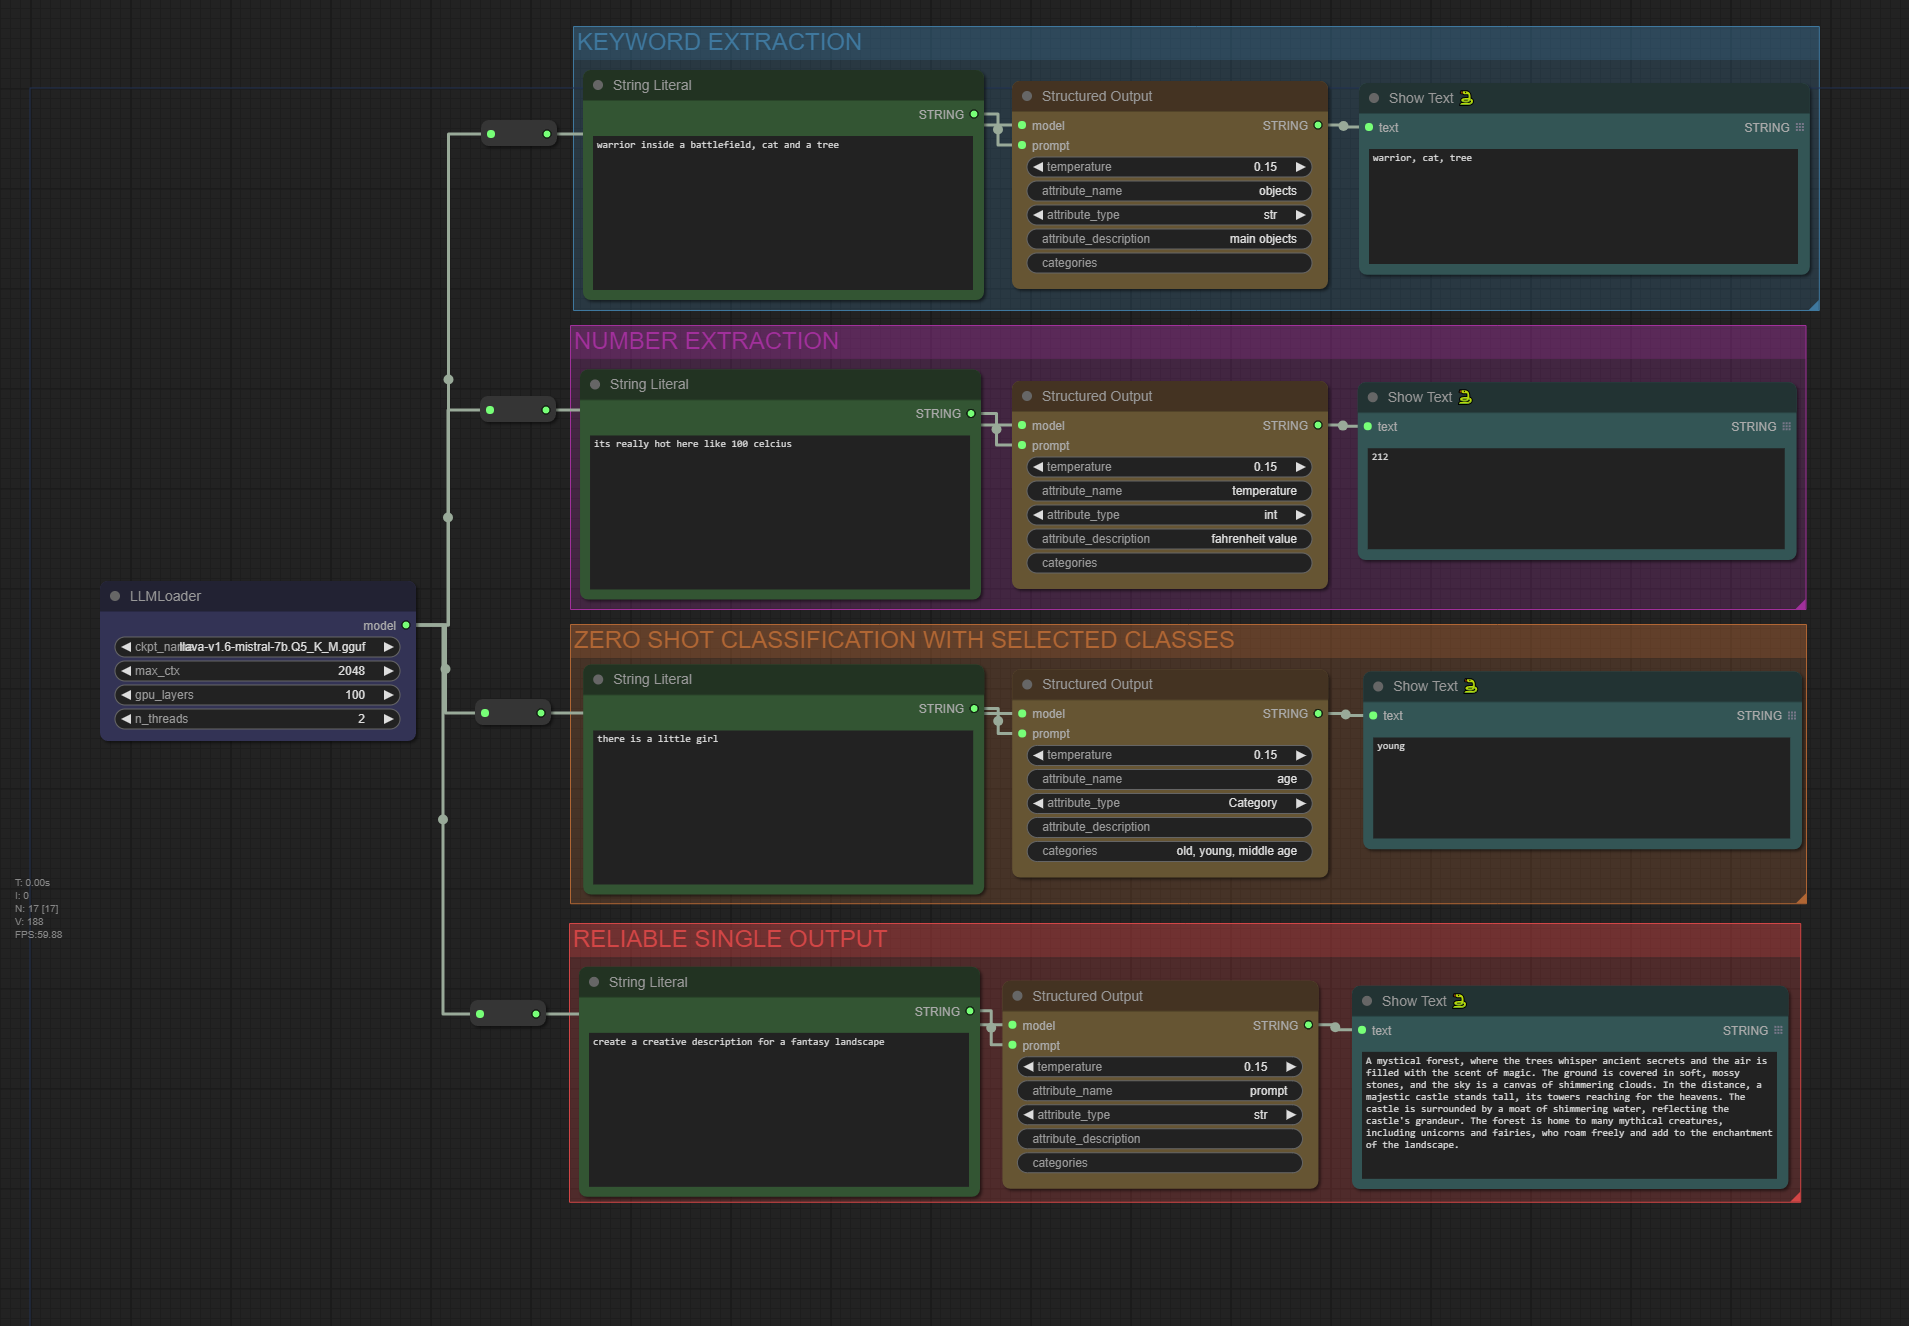
|
||||
- **ComfyUI managed (BF16)** is the default and preferred path. BF16 is used
|
||||
only when the active device reports support; otherwise the node safely falls
|
||||
back to FP16 on CUDA/ROCm/Metal/XPU or FP32 on CPU.
|
||||
- **4-bit/8-bit** models and llama.cpp own external allocators. Before loading,
|
||||
the nodes ask ComfyUI to free the required space; unloading closes the exact
|
||||
owned model and then requests a soft cache cleanup. Small quantized models
|
||||
stay on ComfyUI's active device instead of assuming GPU zero. Large-model
|
||||
Accelerate placement is enabled on CUDA/ROCm/XPU; any disk offload remains
|
||||
inside the model's ComfyUI directory.
|
||||
- `unload_after=false` caches one model per node instance for fast repeated
|
||||
queues. Turn it on for maximum reclamation between prompts.
|
||||
- A connected `video_frames` batch becomes the primary visual input. The
|
||||
optional still-image socket is ignored for video inference so smaller models
|
||||
cannot silently answer from the wrong media.
|
||||
- Qwen 3.5/3.6 thinking is off by default for lower latency and predictable
|
||||
output length; enable it explicitly for tasks that benefit from visual
|
||||
reasoning.
|
||||
- **Auto (SDPA)** is portable and preferred. Flash Attention 2 is accepted only
|
||||
on supported CUDA/ROCm builds and otherwise fails before model loading.
|
||||
- **VLM Runtime Diagnostics** produces a zero-download JSON report containing
|
||||
OS, Python, PyTorch, backend, dtype capability, and optional package versions.
|
||||
- Visualization-only companion repositories do not allocate accelerator memory.
|
||||
|
||||
## Image to Music
|
||||
Utilizes VLMs, LLMs and [AudioLDM-2](https://arxiv.org/abs/2308.05734) to make music from images.
|
||||
Use SaveAudioNode to save the music inside ```output``` folder.
|
||||
It will automatically download the necessary files into ```models/LLavacheckpoints/files_for_audioldm2```
|
||||
Avoid placing several independently quantized VLMs in one workflow unless the
|
||||
GPU can hold them. On a 24 GB card, Qwen 3 VL 2B is the fast default,
|
||||
Qwen 3 VL 8B fits in BF16, and larger models should use NF4. Qwen 3.5/3.6 can
|
||||
be substantially slower when their optional optimized linear-attention kernels
|
||||
are not available for the installed PyTorch/backend combination.
|
||||
|
||||
https://github.com/gokayfem/ComfyUI_VLM_nodes/assets/88277926/2c5bdcde-d637-49ad-b317-14ac0a12f7df
|
||||
## API nodes
|
||||
|
||||
## LLM to Music
|
||||
Utilizes Chat Musician, an open-source LLM that integrates intrinsic musical abilities.
|
||||
[ChatMusician Demo Page](https://ezmonyi.github.io/ChatMusician/)
|
||||
You can try prompts from this demo page.
|
||||
`PromptGenerateAPI` supports the current OpenAI Responses API, the legacy Chat
|
||||
Completions API, and compatible base URLs. API keys can be supplied by node or
|
||||
environment (`OPENAI_API_KEY`, `ANTHROPIC_API_KEY`, `GEMINI_API_KEY`,
|
||||
`GROQ_API_KEY`). Keys are never persisted by this repository.
|
||||
|
||||
**Download the GGUF file**
|
||||
[ChatMusician GGUF Files](https://huggingface.co/MaziyarPanahi/ChatMusician-GGUF/tree/main)
|
||||
**ChatMusician.Q5_K_M.gguf** or **ChatMusician.Q5_K_S.gguf** recommended
|
||||
### BIG BIG BIG Warning: It **does NOT work perfectly**, if you got errors accept the error **queue prompt** again with the same settings!!
|
||||
## Reliability guarantees
|
||||
|
||||
https://github.com/gokayfem/ComfyUI_VLM_nodes/assets/88277926/7f22d4f2-b998-402e-88c8-c382a730d624
|
||||
- Importing the pack performs no network access, compilation, or package install.
|
||||
- Missing optional backends fail only the node that needs them, with an
|
||||
actionable error.
|
||||
- Image inputs use ComfyUI `BHWC` batches; text responses preserve every batch
|
||||
item. Florence/PaLI masks use `BHW`.
|
||||
- `forceInput` string hacks were removed, preventing frontend widget-index drift.
|
||||
- Downloads stay inside the configured ComfyUI model directory.
|
||||
- CI installs and imports the full pack on Linux Python 3.10/3.13, Windows
|
||||
Python 3.12, and macOS Python 3.12. Backend contracts for CUDA, ROCm, Metal,
|
||||
XPU, and CPU are exercised without pretending hosted CPU runners are GPUs.
|
||||
|
||||
## InternLM-XComposer2-VL Node
|
||||
Utilizes ```AutoGPTQ``` for integration of InternLM-XComposer2-VL Model. It will automatically download the necessary files into ```models/LLavacheckpoints/files_for_internlm```.
|
||||
This is one of the best models for visual perception.
|
||||
**Important Note : This model is heavy.**
|
||||
- [InternLM-XComposer2](https://huggingface.co/internlm/internlm-xcomposer2-vl-7b-4bit)
|
||||
Run local checks with:
|
||||
|
||||
## Automatic Prompt Generation and Suggestion Nodes
|
||||
**Get Keyword** node: It can take LLava outputs and extract keywords from them.
|
||||
**LLava PromptGenerator** node: It can create prompts given descriptions or keywords using (input prompt could be Get Keyword or LLava output directly).
|
||||
**Suggester** node: It can generate 5 different prompts based on the original prompt using consistent in the options or random prompts using random in the options.
|
||||
- Works best with **LLava 1.5** and **1.6**.
|
||||
```bash
|
||||
PYTHONPATH=/path/to:/path/to/ComfyUI python -m pytest -q
|
||||
```
|
||||
|
||||
**Play with the ```temperature``` for creative or consistent results. Higher the temperature more creative are the results.**
|
||||
If you want to dive deep into [LLM Settings](https://www.promptingguide.ai/introduction/settings)
|
||||
Real-weight checks are opt-in because they download multi-gigabyte checkpoints:
|
||||
|
||||
Outputs are JSON looking texts, you can see them as a text using JsonToText Node.
|
||||
You can see any string output with ViewText Node
|
||||
You can set any string input using SimpleText Node
|
||||
Utilizes ```llama-cpp-agents``` for getting structured outputs.
|
||||
## LLM Prompt Generation from text nodes
|
||||
```bash
|
||||
python tests/manual_model_smoke.py --model "Qwen 3 VL 4B Instruct"
|
||||
python tests/manual_specialized_smoke.py --backend florence-large
|
||||
```
|
||||
|
||||
**LLM PromptGenerator** node:
|
||||
[Qwen 1.8B Stable Diffusion Prompt](https://huggingface.co/hahahafofo/Qwen-1_8B-Stable-Diffusion-Prompt-GGUF)
|
||||
[IF prompt MKR](https://huggingface.co/impactframes/IFpromptMKR-7b-L2-gguf-q4_k_m)
|
||||
This LLM's works best for now for prompt generation.
|
||||
**LLMSampler** node: You can chat with any LLM in gguf format, you can use LLava models as an LLM also.
|
||||
|
||||
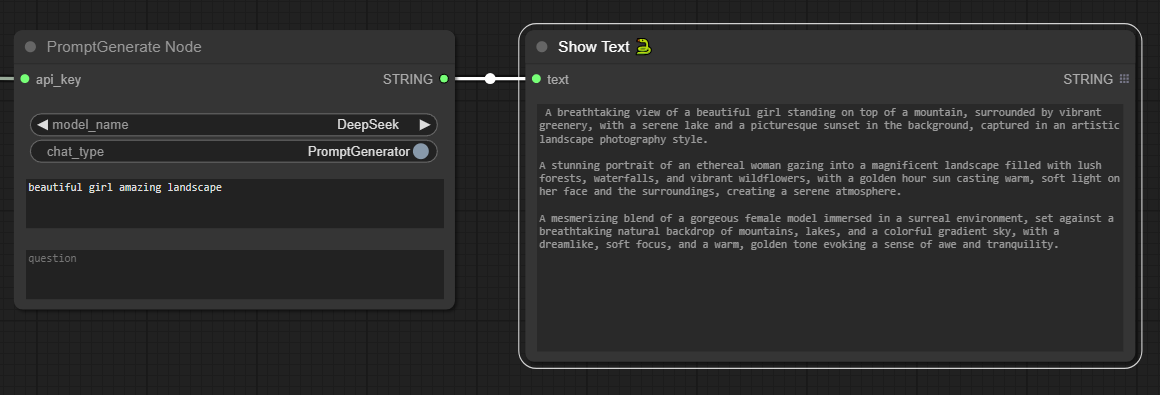
**API PromptGenerator** node: You can use ChatGPT and DeepSeek API's to create prompts. https://platform.deepseek.com/ gives 10m free tokens.
|
||||
- ChatGPT-4
|
||||
- ChatGPT-3.5
|
||||
- DeepSeek
|
||||
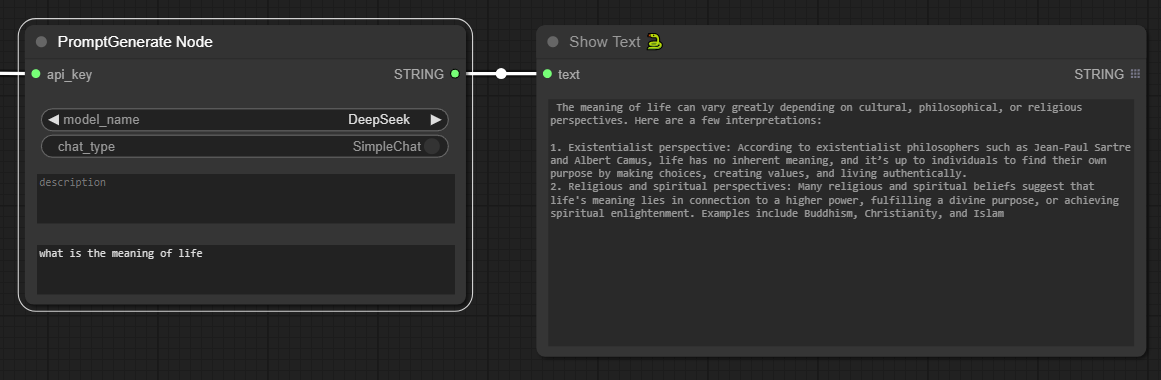
You can use them for simple chat also there is an option in the node.
|
||||
|
||||
## UForm-Gen2 Qwen Node
|
||||
UForm-Gen2 is an extremely fast small generative vision-language model primarily designed for Image Captioning and Visual Question Answering.
|
||||
[UForm-Gen2 Qwen](https://huggingface.co/unum-cloud/uform-gen2-qwen-500m)
|
||||
It will automatically download the necessary files into ```models/LLavacheckpoints/files_for_uform_gen2_qwen```
|
||||
|
||||
## Kosmos-2 Node
|
||||
Kosmos-2: Grounding Multimodal Large Language Models to the World.
|
||||
[Kosmos-2](https://huggingface.co/microsoft/kosmos-2-patch14-224)
|
||||
It will automatically download the necessary files into ```models/LLavacheckpoints/files_for_kosmos2```
|
||||
|
||||
## moondream1 and moondream2 Node
|
||||
This node is designed to work with the Moondream model, a powerful small vision language model built by @vikhyatk using SigLIP, Phi-1.5, and the LLaVa training dataset.
|
||||
The model boasts 1.6 billion parameters and is made available for research purposes only; commercial use is not allowed.
|
||||
|
||||
moondream2 is a small vision language model designed to run efficiently on edge devices.
|
||||
|
||||
It will automatically download the necessary files into ```models/LLavacheckpoints/files_for__moondream``` and ```models/LLavacheckpoints/files_for_moondream2```
|
||||
|
||||
## JoyTag Node
|
||||
@fpgamine's JoyTag is a state of the art AI vision model for tagging images, with a focus on sex positivity and inclusivity.
|
||||
It uses the Danbooru tagging schema, but works across a wide range of images, from hand drawn to photographic.
|
||||
It will automatically download the necessary files into ```models/LLavacheckpoints/files_for_joytagger```
|
||||
|
||||
## Qwen2-VL Node
|
||||
Utilizes the latest Qwen2-VL series of models, which are state-of-the-art vision language models supporting various resolutions, ratios, and languages. The models excel at:
|
||||
- Understanding images of various resolutions & ratios
|
||||
- Complex visual reasoning and decision making
|
||||
- Multilingual support (English, Chinese, European languages, Japanese, Korean, Arabic, Vietnamese, etc.)
|
||||
|
||||
Available models include 2B, 7B, and 72B parameter versions, with standard, AWQ, and GPTQ quantized variants. It will automatically download the necessary files into `models/LLavacheckpoints/files_for_qwen2vl`.
|
||||
|
||||
**Important Note**: Larger models (7B, 72B) require significant VRAM. Choose quantized versions (AWQ, GPTQ) for reduced memory usage.
|
||||
|
||||
[Link to Qwen2-VL Models](https://huggingface.co/Qwen/Qwen2-VL-7B-Instruct)
|
||||
|
||||
## Example LLaVa Nodes
|
||||
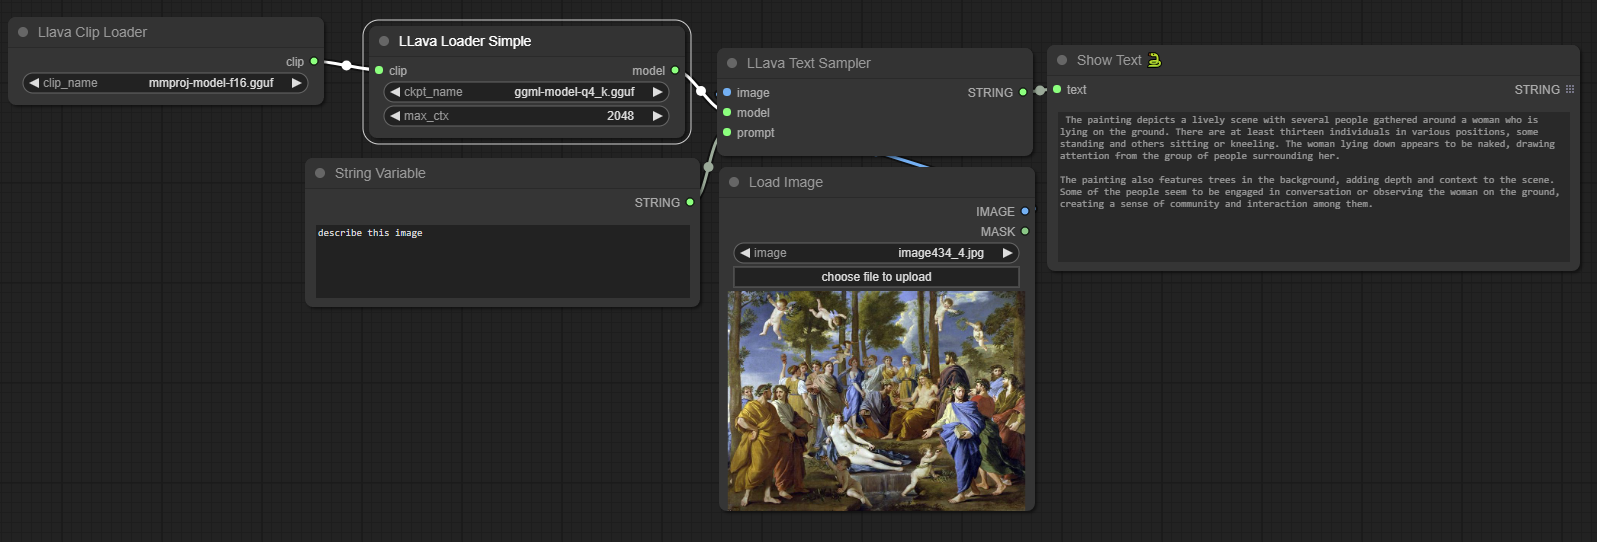
|
||||
|
||||
## Example Image to Music
|
||||
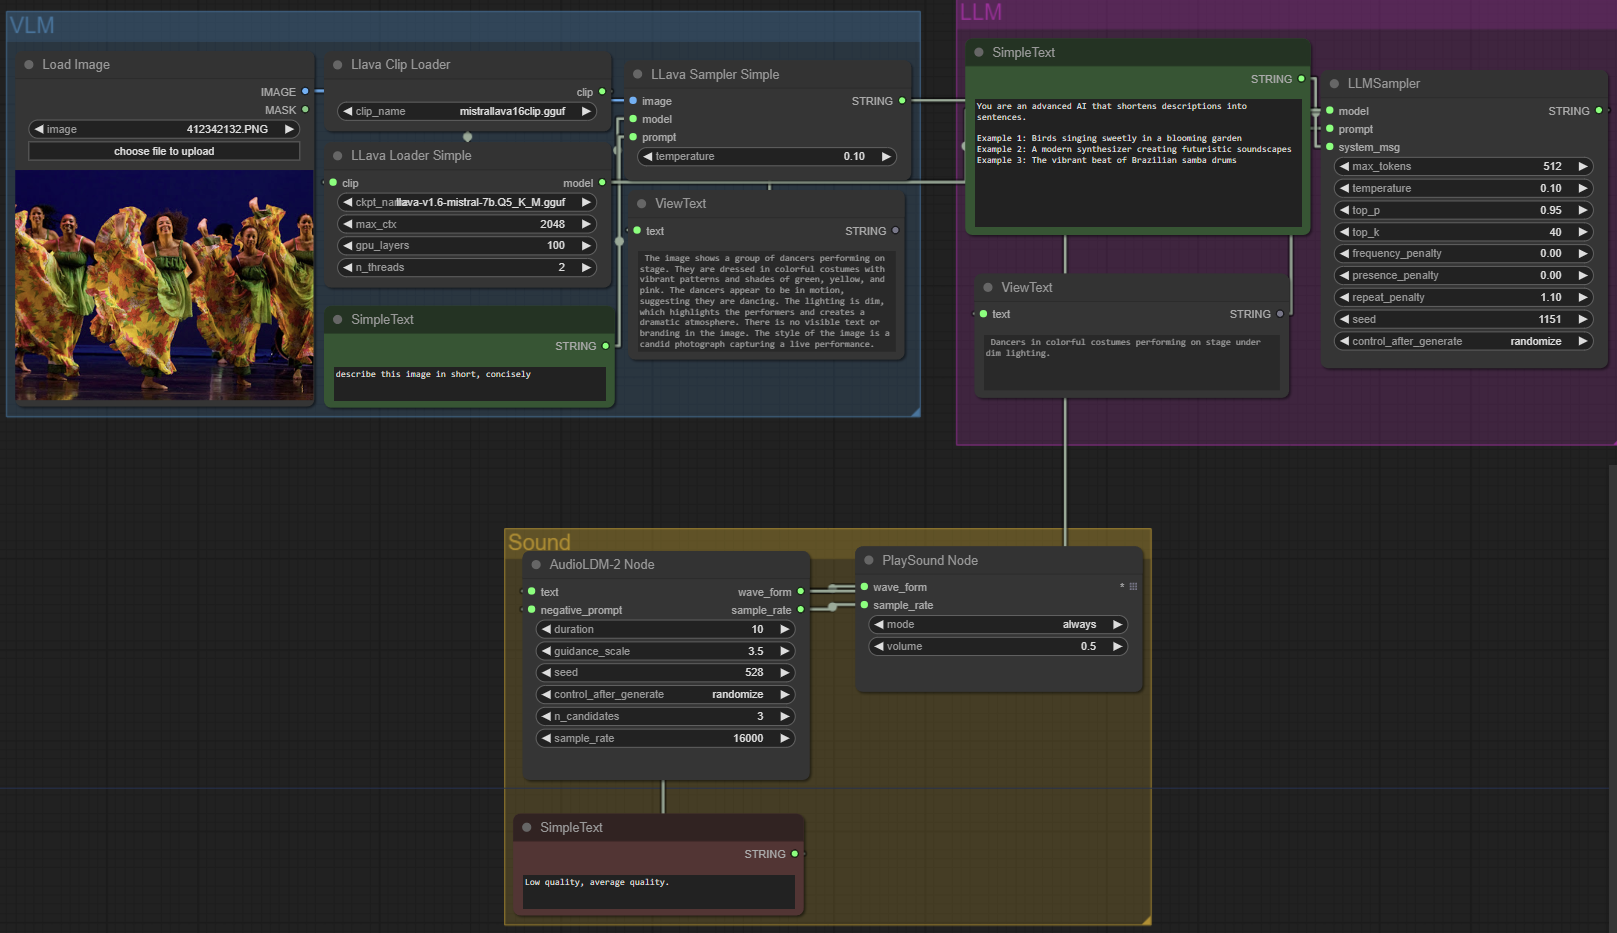
|
||||
|
||||
## Example InternLM-XComposer Node
|
||||
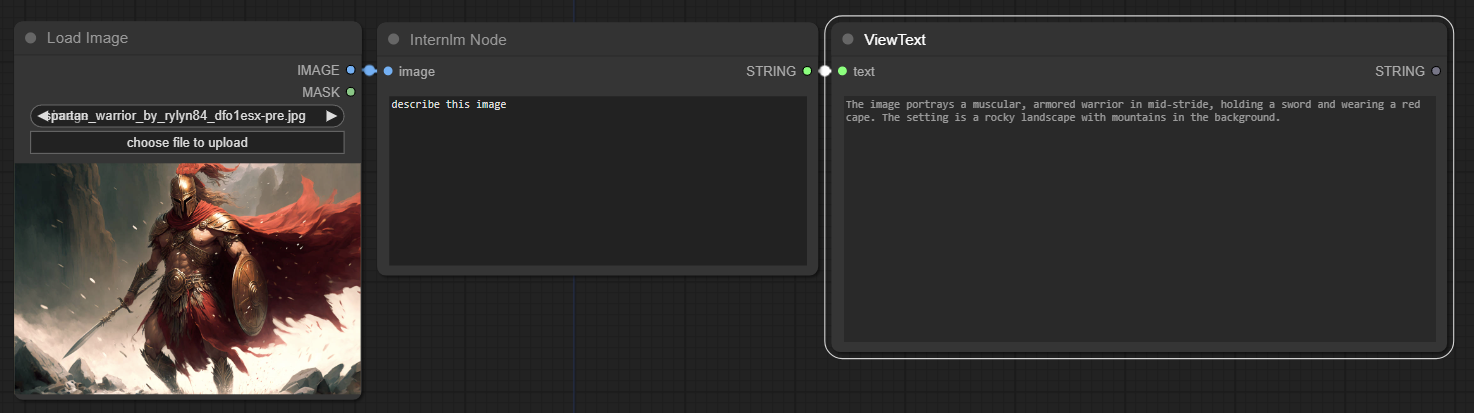
|
||||
|
||||
## Example Using Automatic Prompt Generation
|
||||
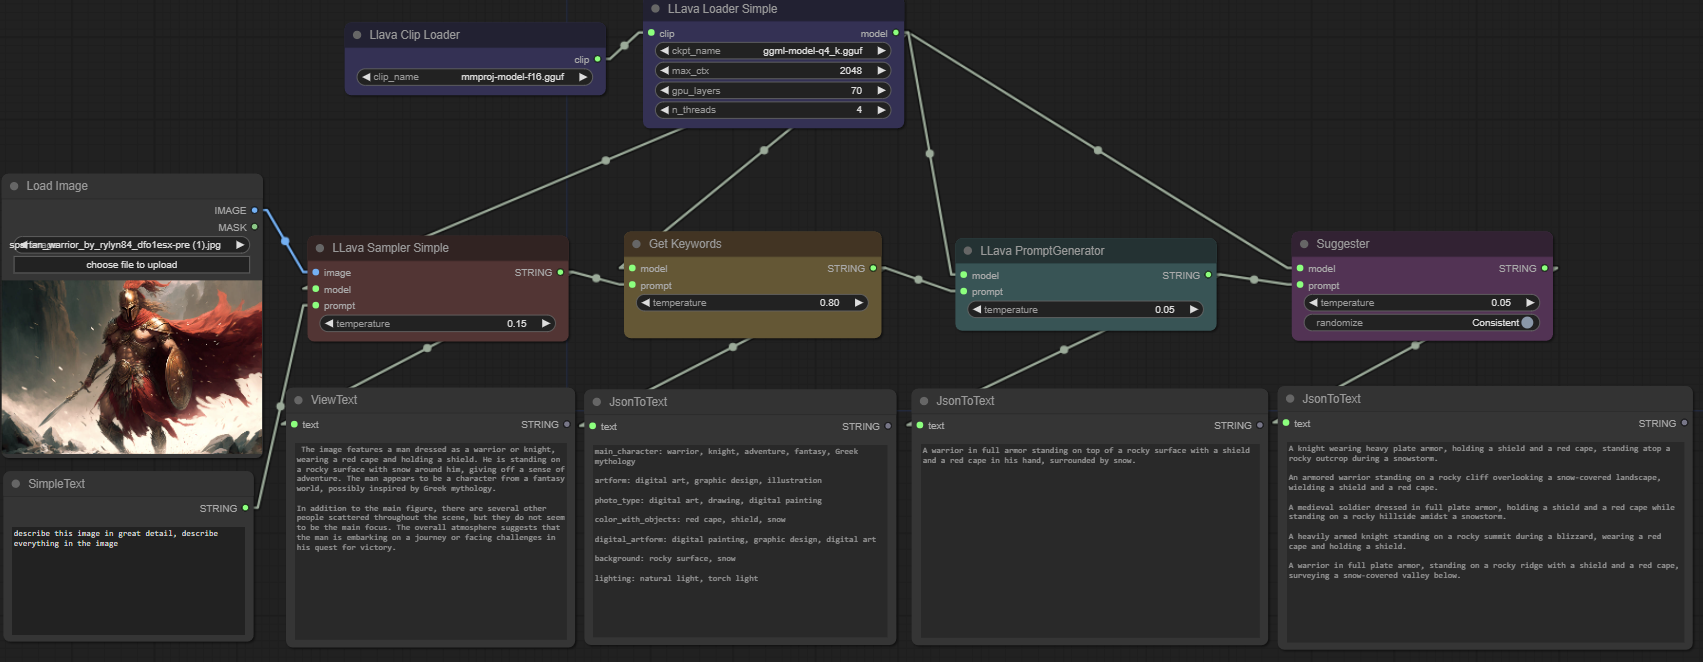
|
||||
|
||||
## LLM Nodes
|
||||

|
||||
|
||||
## Example UForm-Gen2 Qwen Node
|
||||
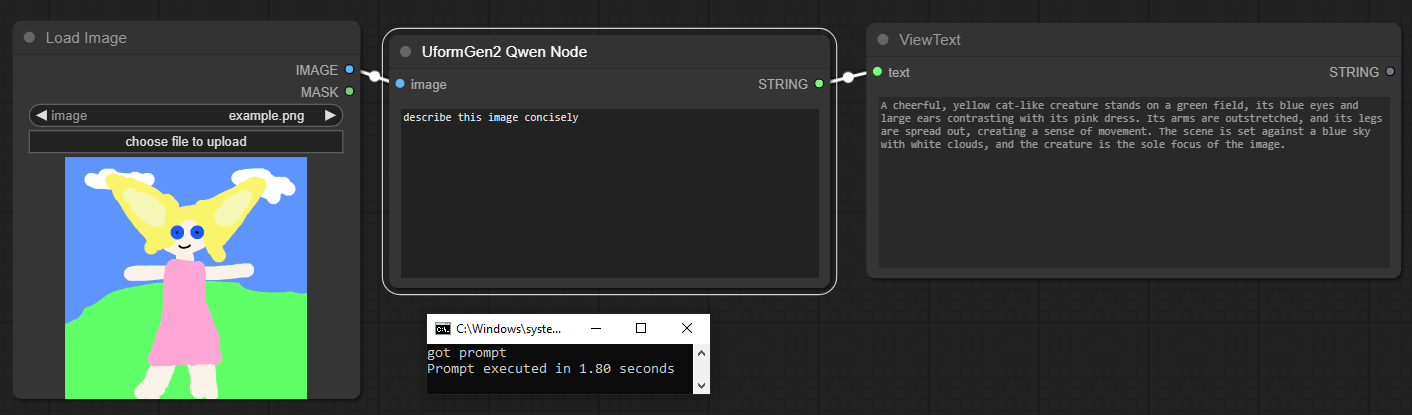
|
||||
|
||||
# Example Kosmos-2 Node
|
||||
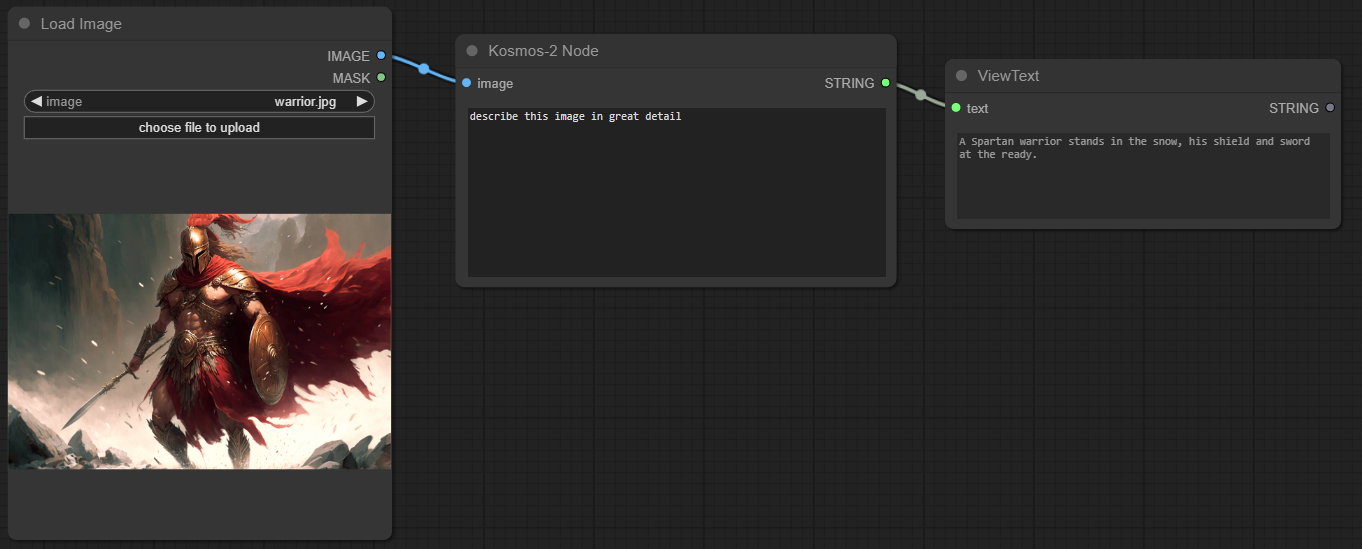
|
||||
|
||||
## Example moondream
|
||||
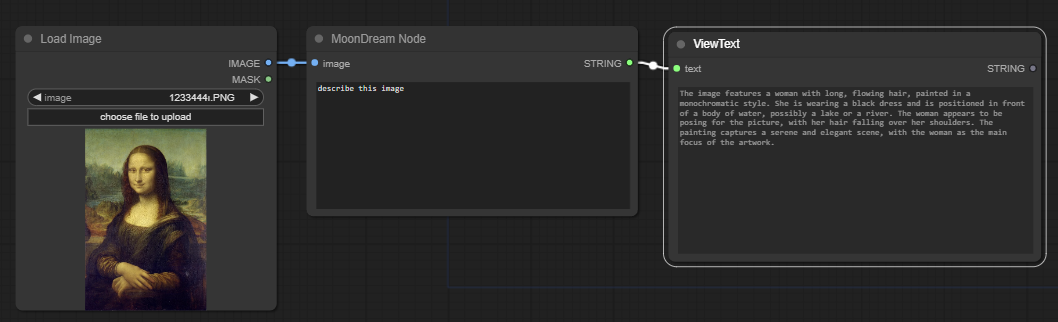
|
||||
|
||||
## Example Joytag
|
||||

|
||||
|
||||
## Example Prompt Generation
|
||||
|
||||
|
||||
## Example SimpleChat
|
||||
|
||||
|
||||
## Example LLava Sampler Advanced
|
||||
|
||||
See [MODEL_VALIDATION.md](MODEL_VALIDATION.md) for the exact real-weight and
|
||||
catalog-only evidence matrix.
|
||||
|
||||
Please report reproducible bugs at the
|
||||
[issue tracker](https://github.com/gokayfem/ComfyUI_VLM_nodes/issues).
|
||||
|
||||
+26
-50
@@ -1,59 +1,21 @@
|
||||
import importlib.util
|
||||
import os
|
||||
import importlib
|
||||
import pkg_resources
|
||||
import sys
|
||||
import subprocess
|
||||
import folder_paths
|
||||
import logging
|
||||
|
||||
supported_LLava_extensions = set(['.gguf'])
|
||||
from .nodes.runtime import register_model_folder
|
||||
|
||||
try:
|
||||
folder_paths.folder_names_and_paths["LLavacheckpoints"] = (folder_paths.folder_names_and_paths["LLavacheckpoints"][0], supported_LLava_extensions)
|
||||
except:
|
||||
# check if LLavacheckpoints exists otherwise create
|
||||
if not os.path.isdir(os.path.join(folder_paths.models_dir, "LLavacheckpoints")):
|
||||
os.mkdir(os.path.join(folder_paths.models_dir, "LLavacheckpoints"))
|
||||
|
||||
folder_paths.folder_names_and_paths["LLavacheckpoints"] = ([os.path.join(folder_paths.models_dir, "LLavacheckpoints")], supported_LLava_extensions)
|
||||
|
||||
# Define the check_requirements_installed function here or import it
|
||||
def check_requirements_installed(requirements_path):
|
||||
with open(requirements_path, 'r') as f:
|
||||
requirements = [pkg_resources.Requirement.parse(line.strip()) for line in f if line.strip()]
|
||||
|
||||
installed_packages = {pkg.key: pkg for pkg in pkg_resources.working_set}
|
||||
installed_packages_set = set(installed_packages.keys())
|
||||
missing_packages = []
|
||||
for requirement in requirements:
|
||||
if requirement.key not in installed_packages_set or not installed_packages[requirement.key] in requirement:
|
||||
missing_packages.append(str(requirement))
|
||||
|
||||
if missing_packages:
|
||||
print(f"Missing or outdated packages: {', '.join(missing_packages)}")
|
||||
print("Installing/Updating missing packages...")
|
||||
subprocess.check_call([sys.executable, '-s', '-m', 'pip', 'install', *missing_packages])
|
||||
else:
|
||||
print("All packages from requirements.txt are installed and up to date.")
|
||||
|
||||
requirements_path = os.path.join(os.path.dirname(os.path.realpath(__file__)), "requirements.txt")
|
||||
check_requirements_installed(requirements_path)
|
||||
|
||||
from .install_init import init, get_system_info, install_llama
|
||||
system_info = get_system_info()
|
||||
install_llama(system_info)
|
||||
llama_cpp_agent_path = os.path.join(os.path.dirname(os.path.realpath(__file__)), "cpp_agent_req.txt")
|
||||
check_requirements_installed(llama_cpp_agent_path)
|
||||
|
||||
init()
|
||||
LOGGER = logging.getLogger("ComfyUI_VLM_nodes")
|
||||
register_model_folder()
|
||||
|
||||
node_list = [
|
||||
"audioldm2",
|
||||
"diagnostics",
|
||||
"florence2",
|
||||
"joytag",
|
||||
"kosmos2",
|
||||
"llavaloader",
|
||||
"mcllava",
|
||||
"minicpm",
|
||||
"modern_vlm",
|
||||
"molmo",
|
||||
"moondream2",
|
||||
"moondream_script",
|
||||
@@ -67,13 +29,27 @@ node_list = [
|
||||
|
||||
NODE_CLASS_MAPPINGS = {}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {}
|
||||
IMPORT_ERRORS = {}
|
||||
|
||||
for module_name in node_list:
|
||||
imported_module = importlib.import_module(f".nodes.{module_name}", __name__)
|
||||
|
||||
NODE_CLASS_MAPPINGS = {**NODE_CLASS_MAPPINGS, **imported_module.NODE_CLASS_MAPPINGS}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {**NODE_DISPLAY_NAME_MAPPINGS, **imported_module.NODE_DISPLAY_NAME_MAPPINGS}
|
||||
try:
|
||||
imported_module = importlib.import_module(f".nodes.{module_name}", __name__)
|
||||
except Exception as exc:
|
||||
# A broken optional model must never prevent unrelated nodes from loading.
|
||||
IMPORT_ERRORS[module_name] = f"{type(exc).__name__}: {exc}"
|
||||
LOGGER.exception("Could not load optional node module %s", module_name)
|
||||
continue
|
||||
NODE_CLASS_MAPPINGS.update(
|
||||
getattr(imported_module, "NODE_CLASS_MAPPINGS", {})
|
||||
)
|
||||
NODE_DISPLAY_NAME_MAPPINGS.update(
|
||||
getattr(imported_module, "NODE_DISPLAY_NAME_MAPPINGS", {})
|
||||
)
|
||||
|
||||
|
||||
WEB_DIRECTORY = "./web"
|
||||
__all__ = ["NODE_CLASS_MAPPINGS", "NODE_DISPLAY_NAME_MAPPINGS", "WEB_DIRECTORY"]
|
||||
__all__ = [
|
||||
"NODE_CLASS_MAPPINGS",
|
||||
"NODE_DISPLAY_NAME_MAPPINGS",
|
||||
"WEB_DIRECTORY",
|
||||
]
|
||||
|
||||
@@ -1,5 +0,0 @@
|
||||
llama-cpp-agent
|
||||
mkdocs
|
||||
mkdocs-material
|
||||
mkdocstrings[python]
|
||||
docstring-parser
|
||||
-486
@@ -1,486 +0,0 @@
|
||||
import os
|
||||
import json
|
||||
import shutil
|
||||
from os.path import join, dirname, abspath, exists
|
||||
from os import makedirs, symlink, readlink
|
||||
import platform
|
||||
import subprocess
|
||||
import sys
|
||||
import importlib.util
|
||||
import re
|
||||
import torch
|
||||
import cpuinfo
|
||||
import packaging.tags
|
||||
from requests import get
|
||||
import asyncio
|
||||
import inspect
|
||||
import aiohttp
|
||||
from server import PromptServer
|
||||
from tqdm import tqdm
|
||||
import pkg_resources
|
||||
|
||||
def verify_python_support():
|
||||
"""Verify Python version meets minimum requirements."""
|
||||
version = tuple(map(int, platform.python_version_tuple()[:2]))
|
||||
if version < (3, 8):
|
||||
print("Warning: Python 3.8 or higher is required")
|
||||
return False
|
||||
return True
|
||||
|
||||
def verify_pypy_support(system_info):
|
||||
"""Verify if the current PyPy version/platform combination is supported."""
|
||||
if 'pp' in system_info['python_version']:
|
||||
pp_ver = system_info['python_version'][2:4]
|
||||
if pp_ver not in ['38', '39', '310']:
|
||||
print("Warning: Current PyPy version may not be supported")
|
||||
return False
|
||||
if system_info['platform_tag'] not in ['linux_i686', 'linux_x86_64', 'win_amd64',
|
||||
'macosx_10_15_x86_64', 'macosx_10_9_x86_64']:
|
||||
print("Warning: Current platform may not be supported for PyPy")
|
||||
return False
|
||||
return True
|
||||
|
||||
def get_python_version():
|
||||
"""Return the Python version in a format matching wheel tags, e.g., 'cp39' for Python 3.9."""
|
||||
version = platform.python_version_tuple()[:2]
|
||||
impl = 'pp' if platform.python_implementation().lower() == 'pypy' else 'cp'
|
||||
return f"{impl}{version[0]}{version[1]}"
|
||||
|
||||
def get_system_info():
|
||||
"""Gather system information related to platform architecture, Python version, and OS."""
|
||||
system_info = {
|
||||
'gpu': False,
|
||||
'cuda_version': None,
|
||||
'rocm_version': None,
|
||||
'python_version': get_python_version(),
|
||||
'os': platform.system().lower(),
|
||||
'arch': platform.machine().lower(),
|
||||
'platform_tag': None
|
||||
}
|
||||
|
||||
# Determine platform-specific tags
|
||||
if system_info['os'] == 'linux':
|
||||
if system_info['arch'] == 'x86_64':
|
||||
system_info['platform_tag'] = 'linux_x86_64'
|
||||
elif system_info['arch'] == 'i686':
|
||||
system_info['platform_tag'] = 'linux_i686'
|
||||
elif system_info['arch'] == 'aarch64':
|
||||
system_info['platform_tag'] = 'linux_aarch64'
|
||||
elif system_info['os'] == 'windows':
|
||||
if system_info['arch'] == 'amd64':
|
||||
system_info['platform_tag'] = 'win_amd64'
|
||||
elif system_info['arch'] == 'x86':
|
||||
system_info['platform_tag'] = 'win32'
|
||||
elif system_info['os'] == 'darwin':
|
||||
if system_info['arch'] == 'x86_64':
|
||||
# Intel Mac
|
||||
if 'pp' in system_info['python_version']:
|
||||
system_info['platform_tag'] = 'macosx_10_15_x86_64'
|
||||
else:
|
||||
py_ver = int(system_info['python_version'][3:])
|
||||
if py_ver >= 12:
|
||||
system_info['platform_tag'] = 'macosx_10_13_x86_64'
|
||||
else:
|
||||
system_info['platform_tag'] = 'macosx_10_9_x86_64'
|
||||
elif system_info['arch'] == 'arm64':
|
||||
# Apple Silicon (M1/M2/M3)
|
||||
print("Apple Silicon detected. llama-cpp-python will be built with Metal support")
|
||||
system_info['platform_tag'] = None # Force source build for optimal Metal support
|
||||
system_info['metal'] = True
|
||||
|
||||
# Check for GPU support
|
||||
if importlib.util.find_spec('torch'):
|
||||
try:
|
||||
import torch
|
||||
if hasattr(torch.version, 'hip') and torch.version.hip is not None:
|
||||
system_info['gpu'] = True
|
||||
system_info['rocm_version'] = f"rocm{torch.version.hip}"
|
||||
elif torch.cuda.is_available():
|
||||
system_info['gpu'] = True
|
||||
system_info['cuda_version'] = "cu" + torch.version.cuda.replace(".", "").strip()
|
||||
except:
|
||||
pass
|
||||
|
||||
return system_info
|
||||
|
||||
def latest_lamacpp():
|
||||
"""Fetch the latest version of llama-cpp-python, with fallback."""
|
||||
try:
|
||||
response = get("https://api.github.com/repos/abetlen/llama-cpp-python/releases/latest", timeout=10)
|
||||
response.raise_for_status()
|
||||
return response.json()["tag_name"].replace("v", "")
|
||||
except Exception as e:
|
||||
print(f"Failed to fetch latest version: {e}")
|
||||
return "0.3.1" # Fallback to known working version
|
||||
|
||||
def package_is_installed(package_name):
|
||||
"""Check if a Python package is installed."""
|
||||
return importlib.util.find_spec(package_name) is not None
|
||||
|
||||
def install_package(package_name, extra_args=None):
|
||||
"""Install a Python package with pip."""
|
||||
command = [sys.executable, "-m", "pip", "install", package_name, "--no-cache-dir"]
|
||||
if extra_args:
|
||||
command.extend(extra_args.split())
|
||||
subprocess.check_call(command)
|
||||
|
||||
def install_llama(system_info):
|
||||
"""Install llama-cpp-python using the appropriate method based on system capabilities."""
|
||||
if not verify_python_support():
|
||||
print("ERROR: Unsupported Python version")
|
||||
return False
|
||||
|
||||
if not verify_pypy_support(system_info):
|
||||
print("WARNING: Unsupported PyPy configuration")
|
||||
|
||||
imported = package_is_installed("llama-cpp-python") or package_is_installed("llama_cpp")
|
||||
if imported:
|
||||
print("llama-cpp installed")
|
||||
return True
|
||||
|
||||
# Simple pip install for Linux
|
||||
if system_info['os'] == 'linux':
|
||||
try:
|
||||
print("Installing llama-cpp-python via pip")
|
||||
install_package("llama-cpp-python")
|
||||
return True
|
||||
except Exception as e:
|
||||
print(f"Installation failed: {e}")
|
||||
return False
|
||||
|
||||
# If pre-built wheels fail, try GitHub release wheels
|
||||
try:
|
||||
version = latest_lamacpp()
|
||||
platform_tag = system_info['platform_tag']
|
||||
|
||||
if platform_tag:
|
||||
python_version = system_info['python_version']
|
||||
wheel_name = f"llama_cpp_python-{version}-{python_version}-{python_version}-{platform_tag}.whl"
|
||||
wheel_url = f"https://github.com/abetlen/llama-cpp-python/releases/download/v{version}/{wheel_name}"
|
||||
|
||||
print(f"Attempting to install from {wheel_url}")
|
||||
install_package(wheel_url)
|
||||
print(f"Successfully installed llama-cpp-python v{version}")
|
||||
return True
|
||||
except Exception as e:
|
||||
print(f"GitHub wheel installation failed: {e}")
|
||||
print("Attempting source build with acceleration...")
|
||||
|
||||
# Build from source with appropriate acceleration
|
||||
try:
|
||||
if system_info.get('metal', False):
|
||||
print("Building llama-cpp-python from source with Metal support")
|
||||
os.environ['CMAKE_ARGS'] = "-DGGML_METAL=on"
|
||||
install_package("llama-cpp-python")
|
||||
return True
|
||||
elif system_info['gpu']:
|
||||
if system_info.get('cuda_version'):
|
||||
print("Building llama-cpp-python from source with CUDA support")
|
||||
# Add ZLUDA support check
|
||||
if os.environ.get('ZLUDA_PATH'):
|
||||
print("ZLUDA detected, building with ZLUDA support")
|
||||
os.environ['CMAKE_ARGS'] = "-DGGML_CUDA=on -DGGML_CUDA_ZLUDA=on"
|
||||
else:
|
||||
os.environ['CMAKE_ARGS'] = "-DGGML_CUDA=on"
|
||||
install_package("llama-cpp-python")
|
||||
return True
|
||||
elif system_info.get('rocm_version'):
|
||||
print("Building llama-cpp-python from source with ROCm support")
|
||||
os.environ['CMAKE_ARGS'] = "-DGGML_HIPBLAS=on"
|
||||
install_package("llama-cpp-python")
|
||||
return True
|
||||
except Exception as e:
|
||||
print(f"Accelerated build failed: {e}")
|
||||
print("Falling back to CPU-only version")
|
||||
|
||||
# Final fallback - basic CPU version
|
||||
try:
|
||||
print("Installing CPU-only version")
|
||||
install_package("llama-cpp-python")
|
||||
return True
|
||||
except Exception as e:
|
||||
print(f"CPU installation failed: {e}")
|
||||
return False
|
||||
|
||||
config = None
|
||||
|
||||
def is_logging_enabled():
|
||||
config = get_extension_config()
|
||||
if "logging" not in config:
|
||||
return False
|
||||
return config["logging"]
|
||||
|
||||
def log(message, type=None, always=False, name=None):
|
||||
if not always and not is_logging_enabled():
|
||||
return
|
||||
|
||||
if type is not None:
|
||||
message = f"[{type}] {message}"
|
||||
|
||||
if name is None:
|
||||
name = get_extension_config()["name"]
|
||||
|
||||
print(f"(vlmnodes:{name}) {message}")
|
||||
|
||||
def get_ext_dir(subpath=None, mkdir=False):
|
||||
dir = os.path.dirname(__file__)
|
||||
if subpath is not None:
|
||||
dir = os.path.join(dir, subpath)
|
||||
|
||||
dir = os.path.abspath(dir)
|
||||
|
||||
if mkdir and not os.path.exists(dir):
|
||||
os.makedirs(dir)
|
||||
return dir
|
||||
|
||||
def get_comfy_dir(subpath=None, mkdir=False):
|
||||
dir = os.path.dirname(inspect.getfile(PromptServer))
|
||||
if subpath is not None:
|
||||
dir = os.path.join(dir, subpath)
|
||||
|
||||
dir = os.path.abspath(dir)
|
||||
|
||||
if mkdir and not os.path.exists(dir):
|
||||
os.makedirs(dir)
|
||||
return dir
|
||||
|
||||
def get_web_ext_dir():
|
||||
config = get_extension_config()
|
||||
name = config["name"]
|
||||
dir = get_comfy_dir("web/extensions/vlmnodes")
|
||||
if not os.path.exists(dir):
|
||||
os.makedirs(dir)
|
||||
dir = os.path.join(dir, name)
|
||||
return dir
|
||||
|
||||
|
||||
def get_extension_config(reload=False):
|
||||
global config
|
||||
if reload == False and config is not None:
|
||||
return config
|
||||
|
||||
config_path = get_ext_dir("vlmnodes.json")
|
||||
default_config_path = get_ext_dir("vlmnodes.default.json")
|
||||
if not os.path.exists(config_path):
|
||||
if os.path.exists(default_config_path):
|
||||
shutil.copy(default_config_path, config_path)
|
||||
if not os.path.exists(config_path):
|
||||
log(f"Failed to create config at {config_path}", type="ERROR", always=True, name="???")
|
||||
print(f"Extension path: {get_ext_dir()}")
|
||||
return {"name": "Unknown", "version": -1}
|
||||
|
||||
else:
|
||||
log("Missing pysssss.default.json, this extension may not work correctly. Please reinstall the extension.",
|
||||
type="ERROR", always=True, name="???")
|
||||
print(f"Extension path: {get_ext_dir()}")
|
||||
return {"name": "Unknown", "version": -1}
|
||||
|
||||
with open(config_path, "r") as f:
|
||||
config = json.loads(f.read())
|
||||
return config
|
||||
|
||||
def link_js(src, dst):
|
||||
src = os.path.abspath(src)
|
||||
dst = os.path.abspath(dst)
|
||||
if os.name == "nt":
|
||||
try:
|
||||
import _winapi
|
||||
_winapi.CreateJunction(src, dst)
|
||||
return True
|
||||
except:
|
||||
pass
|
||||
try:
|
||||
os.symlink(src, dst)
|
||||
return True
|
||||
except:
|
||||
import logging
|
||||
logging.exception('')
|
||||
return False
|
||||
|
||||
def is_junction(path):
|
||||
if os.name != "nt":
|
||||
return False
|
||||
try:
|
||||
return bool(os.readlink(path))
|
||||
except OSError:
|
||||
return False
|
||||
|
||||
def install_js():
|
||||
src_dir = get_ext_dir("web/js")
|
||||
if not os.path.exists(src_dir):
|
||||
log("No JS")
|
||||
return
|
||||
|
||||
should_install = should_install_js()
|
||||
if should_install:
|
||||
log("it looks like you're running an old version of ComfyUI that requires manual setup of web files, it is recommended you update your installation.", "warning", True)
|
||||
dst_dir = get_web_ext_dir()
|
||||
linked = os.path.islink(dst_dir) or is_junction(dst_dir)
|
||||
if linked or os.path.exists(dst_dir):
|
||||
if linked:
|
||||
if should_install:
|
||||
log("JS already linked")
|
||||
else:
|
||||
os.unlink(dst_dir)
|
||||
log("JS unlinked, PromptServer will serve extension")
|
||||
elif not should_install:
|
||||
shutil.rmtree(dst_dir)
|
||||
log("JS deleted, PromptServer will serve extension")
|
||||
return
|
||||
|
||||
if not should_install:
|
||||
log("JS skipped, PromptServer will serve extension")
|
||||
return
|
||||
|
||||
if link_js(src_dir, dst_dir):
|
||||
log("JS linked")
|
||||
return
|
||||
|
||||
log("Copying JS files")
|
||||
shutil.copytree(src_dir, dst_dir, dirs_exist_ok=True)
|
||||
|
||||
def should_install_js():
|
||||
return not hasattr(PromptServer.instance, "supports") or "custom_nodes_from_web" not in PromptServer.instance.supports
|
||||
|
||||
|
||||
def init(check_imports=None):
|
||||
log("Init")
|
||||
|
||||
if check_imports is not None:
|
||||
import importlib.util
|
||||
for imp in check_imports:
|
||||
spec = importlib.util.find_spec(imp)
|
||||
if spec is None:
|
||||
log(f"{imp} is required, please check requirements are installed.",
|
||||
type="ERROR", always=True)
|
||||
return False
|
||||
|
||||
install_js()
|
||||
return True
|
||||
|
||||
|
||||
def get_async_loop():
|
||||
loop = None
|
||||
try:
|
||||
loop = asyncio.get_event_loop()
|
||||
except:
|
||||
loop = asyncio.new_event_loop()
|
||||
asyncio.set_event_loop(loop)
|
||||
return loop
|
||||
|
||||
|
||||
def get_http_session():
|
||||
loop = get_async_loop()
|
||||
return aiohttp.ClientSession(loop=loop)
|
||||
|
||||
|
||||
async def download(url, stream, update_callback=None, session=None):
|
||||
close_session = False
|
||||
if session is None:
|
||||
close_session = True
|
||||
session = get_http_session()
|
||||
try:
|
||||
async with session.get(url) as response:
|
||||
size = int(response.headers.get('content-length', 0)) or None
|
||||
|
||||
with tqdm(
|
||||
unit='B', unit_scale=True, miniters=1, desc=url.split('/')[-1], total=size,
|
||||
) as progressbar:
|
||||
perc = 0
|
||||
async for chunk in response.content.iter_chunked(2048):
|
||||
stream.write(chunk)
|
||||
progressbar.update(len(chunk))
|
||||
if update_callback is not None and progressbar.total is not None and progressbar.total != 0:
|
||||
last = perc
|
||||
perc = round(progressbar.n / progressbar.total, 2)
|
||||
if perc != last:
|
||||
last = perc
|
||||
await update_callback(perc)
|
||||
finally:
|
||||
if close_session and session is not None:
|
||||
await session.close()
|
||||
|
||||
|
||||
async def download_to_file(url, destination, update_callback=None, is_ext_subpath=True, session=None):
|
||||
if is_ext_subpath:
|
||||
destination = get_ext_dir(destination)
|
||||
with open(destination, mode='wb') as f:
|
||||
download(url, f, update_callback, session)
|
||||
|
||||
|
||||
def wait_for_async(async_fn, loop=None):
|
||||
res = []
|
||||
|
||||
async def run_async():
|
||||
r = await async_fn()
|
||||
res.append(r)
|
||||
|
||||
if loop is None:
|
||||
try:
|
||||
loop = asyncio.get_event_loop()
|
||||
except:
|
||||
loop = asyncio.new_event_loop()
|
||||
asyncio.set_event_loop(loop)
|
||||
|
||||
loop.run_until_complete(run_async())
|
||||
|
||||
return res[0]
|
||||
|
||||
|
||||
def update_node_status(client_id, node, text, progress=None):
|
||||
if client_id is None:
|
||||
client_id = PromptServer.instance.client_id
|
||||
|
||||
if client_id is None:
|
||||
return
|
||||
|
||||
PromptServer.instance.send_sync("vlmnodes/update_status", {
|
||||
"node": node,
|
||||
"progress": progress,
|
||||
"text": text
|
||||
}, client_id)
|
||||
|
||||
|
||||
async def update_node_status_async(client_id, node, text, progress=None):
|
||||
if client_id is None:
|
||||
client_id = PromptServer.instance.client_id
|
||||
|
||||
if client_id is None:
|
||||
return
|
||||
|
||||
await PromptServer.instance.send("vlmnodes/update_status", {
|
||||
"node": node,
|
||||
"progress": progress,
|
||||
"text": text
|
||||
}, client_id)
|
||||
|
||||
|
||||
def get_config_value(key, default=None, throw=False):
|
||||
split = key.split(".")
|
||||
obj = get_extension_config()
|
||||
for s in split:
|
||||
if s in obj:
|
||||
obj = obj[s]
|
||||
else:
|
||||
if throw:
|
||||
raise KeyError("Configuration key missing: " + key)
|
||||
else:
|
||||
return default
|
||||
return obj
|
||||
|
||||
|
||||
def is_inside_dir(root_dir, check_path):
|
||||
root_dir = os.path.abspath(root_dir)
|
||||
if not os.path.isabs(check_path):
|
||||
check_path = os.path.abspath(os.path.join(root_dir, check_path))
|
||||
return os.path.commonpath([check_path, root_dir]) == root_dir
|
||||
|
||||
|
||||
def get_child_dir(root_dir, child_path, throw_if_outside=True):
|
||||
child_path = os.path.abspath(os.path.join(root_dir, child_path))
|
||||
if is_inside_dir(root_dir, child_path):
|
||||
return child_path
|
||||
if throw_if_outside:
|
||||
raise NotADirectoryError(
|
||||
"Saving outside the target folder is not allowed.")
|
||||
return None
|
||||
+186
-98
@@ -1,105 +1,203 @@
|
||||
from huggingface_hub import snapshot_download
|
||||
from pathlib import Path
|
||||
import torch
|
||||
import os
|
||||
import soundfile as sf
|
||||
from folder_paths import output_directory
|
||||
import folder_paths
|
||||
import datetime
|
||||
"""Lazy AudioLDM2 generation with legacy and standard ComfyUI AUDIO outputs."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
# Define the directory for saving files related to the audio model
|
||||
files_for_audio_model = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for_audioldm2"
|
||||
files_for_audio_model.mkdir(parents=True, exist_ok=True) # Ensure the directory exists
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
import folder_paths
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
execution_device,
|
||||
require_module,
|
||||
reserve_external_vram,
|
||||
snapshot_download,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
|
||||
class AnyType(str):
|
||||
def __ne__(self, __value: object) -> bool:
|
||||
def __ne__(self, other):
|
||||
return False
|
||||
base_path = os.path.dirname(os.path.realpath(__file__))
|
||||
|
||||
# Our any instance wants to be a wildcard string
|
||||
any = AnyType("*")
|
||||
class AudioLDM2ModelPredictor:
|
||||
|
||||
def __init__(self):
|
||||
from diffusers import AudioLDM2Pipeline
|
||||
self.device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
torch_dtype = torch.float16 if self.device == "cuda" else torch.float32
|
||||
|
||||
# Use snapshot_download to manage the model download/cache
|
||||
self.model_path = snapshot_download("cvssp/audioldm2",
|
||||
local_dir=files_for_audio_model,
|
||||
force_download=False, # Set to True to always download
|
||||
local_files_only=False, # Download if not available locally
|
||||
use_auth_token=False, # Set to True if using a private model
|
||||
local_dir_use_symlinks="auto", # Auto-manage symlinks
|
||||
ignore_patterns=["*.bin", "*.jpg", "*.png"]) # Ignore unrelated files
|
||||
ANY = AnyType("*")
|
||||
|
||||
self.pipeline = AudioLDM2Pipeline.from_pretrained(self.model_path,
|
||||
torch_dtype=torch_dtype).to(self.device)
|
||||
self.generator = torch.Generator(self.device)
|
||||
|
||||
def generate_audio(self, text, negative_prompt, duration, guidance_scale, random_seed, sample_rate, n_candidates=1, extension="wav"):
|
||||
if text is None:
|
||||
raise ValueError("Please provide a text input.")
|
||||
|
||||
# Manual seed for reproducibility
|
||||
self.generator.manual_seed(int(random_seed))
|
||||
class AudioLDM2Predictor:
|
||||
def __init__(self, cpu_offload=True):
|
||||
diffusers = require_module("diffusers")
|
||||
path = snapshot_download(
|
||||
"cvssp/audioldm2",
|
||||
"audioldm2",
|
||||
ignore_patterns=["*.bin", "*.jpg", "*.png"],
|
||||
)
|
||||
self.device = execution_device()
|
||||
dtype = torch_dtype("float16", self.device)
|
||||
if self.device.type != "cpu":
|
||||
reserve_external_vram(8 * 1024**3)
|
||||
self.pipeline = diffusers.AudioLDM2Pipeline.from_pretrained(
|
||||
path, torch_dtype=dtype
|
||||
)
|
||||
# Accelerate's model CPU offload is currently reliable on the CUDA API,
|
||||
# which covers both NVIDIA CUDA and AMD ROCm PyTorch builds.
|
||||
if self.device.type == "cuda" and cpu_offload:
|
||||
require_module("accelerate")
|
||||
self.pipeline.enable_model_cpu_offload()
|
||||
else:
|
||||
self.pipeline.to(self.device)
|
||||
|
||||
# Generate audio
|
||||
waveforms = self.pipeline(
|
||||
def close(self):
|
||||
self.pipeline = None
|
||||
import gc
|
||||
|
||||
gc.collect()
|
||||
try:
|
||||
import comfy.model_management as model_management
|
||||
|
||||
model_management.soft_empty_cache()
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
def generate(self, text, negative, duration, guidance, seed, count, steps):
|
||||
# MPS generators are not supported by every PyTorch/Diffusers pairing.
|
||||
# A CPU generator remains deterministic and works with every pipeline.
|
||||
generator_device = (
|
||||
self.device if self.device.type in {"cuda", "xpu"} else "cpu"
|
||||
)
|
||||
generator = torch.Generator(device=generator_device).manual_seed(
|
||||
int(seed)
|
||||
)
|
||||
audios = self.pipeline(
|
||||
text,
|
||||
audio_length_in_s=duration,
|
||||
guidance_scale=guidance_scale,
|
||||
num_inference_steps=200,
|
||||
negative_prompt=negative_prompt,
|
||||
num_waveforms_per_prompt=n_candidates,
|
||||
generator=self.generator,
|
||||
)["audios"]
|
||||
|
||||
final_waveforms = waveforms[0].tolist()
|
||||
return (final_waveforms, sample_rate) # Return the path of the generated audio file
|
||||
negative_prompt=negative or None,
|
||||
audio_length_in_s=float(duration),
|
||||
guidance_scale=float(guidance),
|
||||
num_inference_steps=int(steps),
|
||||
num_waveforms_per_prompt=int(count),
|
||||
generator=generator,
|
||||
).audios
|
||||
array = np.asarray(audios, dtype=np.float32)
|
||||
if array.ndim == 1:
|
||||
array = array[None, :]
|
||||
native_rate = int(
|
||||
getattr(
|
||||
getattr(getattr(self.pipeline, "vae", None), "config", None),
|
||||
"sampling_rate",
|
||||
16000,
|
||||
)
|
||||
)
|
||||
return array, native_rate
|
||||
|
||||
|
||||
class AudioLDM2Node:
|
||||
def __init__(self):
|
||||
self.predictor = AudioLDM2ModelPredictor()
|
||||
|
||||
class AudioLDM2Node(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"text": ("STRING",{"default": "", "forceInput": True}),
|
||||
"negative_prompt": ("STRING",{"default": "", "forceInput": True}),
|
||||
"duration": ("INT",{"default": 10, "min": 1, "max": 60, "step": 1}),
|
||||
"guidance_scale": ("FLOAT", {"default": 3.5, "min": 0.1, "max": 20.0, "step": 0.1}),
|
||||
"seed": ("INT", {"default": 42, "step": 1}),
|
||||
"n_candidates": ("INT", {"default": 3, "min": 1, "max": 10, "step": 1}),
|
||||
"sample_rate": ("INT", {"default": 16000, "min": 8000, "max": 48000, "step": 1}),
|
||||
"extension": (["wav", "mp3", "flac"], {"default": "wav"}),
|
||||
}
|
||||
"text": ("STRING", {"default": "", "multiline": True}),
|
||||
"negative_prompt": (
|
||||
"STRING",
|
||||
{"default": "", "multiline": True},
|
||||
),
|
||||
"duration": (
|
||||
"INT",
|
||||
{"default": 10, "min": 1, "max": 60},
|
||||
),
|
||||
"guidance_scale": (
|
||||
"FLOAT",
|
||||
{"default": 3.5, "min": 0.1, "max": 20.0, "step": 0.1},
|
||||
),
|
||||
"seed": ("INT", {"default": 42, "min": 0}),
|
||||
"n_candidates": (
|
||||
"INT",
|
||||
{"default": 1, "min": 1, "max": 10},
|
||||
),
|
||||
"sample_rate": (
|
||||
"INT",
|
||||
{"default": 16000, "min": 8000, "max": 48000},
|
||||
),
|
||||
"extension": (["wav", "flac"],),
|
||||
},
|
||||
"optional": {
|
||||
"steps": ("INT", {"default": 100, "min": 10, "max": 500}),
|
||||
"cpu_offload": ("BOOLEAN", {"default": True}),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_NAMES = ("wave_form", "sample_rate", )
|
||||
RETURN_TYPES = (any, "INT", )
|
||||
RETURN_NAMES = ("wave_form", "sample_rate", "audio")
|
||||
RETURN_TYPES = (ANY, "INT", "AUDIO")
|
||||
OUTPUT_NODE = True
|
||||
FUNCTION = "generate_audio_final"
|
||||
|
||||
CATEGORY = "VLM Nodes/Audio"
|
||||
|
||||
def generate_audio_final(self, text, negative_prompt, duration, guidance_scale, sample_rate, seed, n_candidates, extension):
|
||||
wave_form, sample_rate_final = self.predictor.generate_audio(text, negative_prompt, duration, guidance_scale, seed, sample_rate, n_candidates, extension)
|
||||
return (wave_form, sample_rate_final, )
|
||||
def generate_audio_final(
|
||||
self,
|
||||
text,
|
||||
negative_prompt,
|
||||
duration,
|
||||
guidance_scale,
|
||||
sample_rate,
|
||||
seed,
|
||||
n_candidates,
|
||||
extension,
|
||||
steps=100,
|
||||
cpu_offload=True,
|
||||
unload_after=False,
|
||||
):
|
||||
del extension
|
||||
predictor = self.get_or_create_model(
|
||||
("audioldm2", bool(cpu_offload)),
|
||||
lambda: AudioLDM2Predictor(cpu_offload),
|
||||
)
|
||||
try:
|
||||
waveforms, native_rate = predictor.generate(
|
||||
text,
|
||||
negative_prompt,
|
||||
duration,
|
||||
guidance_scale,
|
||||
seed,
|
||||
n_candidates,
|
||||
steps,
|
||||
)
|
||||
if int(sample_rate) != native_rate:
|
||||
samples = torch.from_numpy(waveforms).unsqueeze(1)
|
||||
target_length = round(
|
||||
samples.shape[-1] * int(sample_rate) / native_rate
|
||||
)
|
||||
waveforms = (
|
||||
torch.nn.functional.interpolate(
|
||||
samples,
|
||||
size=target_length,
|
||||
mode="linear",
|
||||
align_corners=False,
|
||||
)
|
||||
.squeeze(1)
|
||||
.numpy()
|
||||
)
|
||||
# Standard Comfy AUDIO is [batch, channels, samples].
|
||||
audio = {
|
||||
"waveform": torch.from_numpy(waveforms).unsqueeze(1),
|
||||
"sample_rate": int(sample_rate),
|
||||
}
|
||||
return (waveforms[0].tolist(), int(sample_rate), audio)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
class SaveAudioNode:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"waveforms": (any, {}),
|
||||
"sample_rate": ("INT", {"forceInput": True}),
|
||||
"extension": (["wav", "mp3", "flac"], {"default": "wav"}),
|
||||
"filename": ("STRING", {"default": "audio", "forceInput": True}) # Input for filename
|
||||
"waveforms": (ANY,),
|
||||
"sample_rate": ("INT",),
|
||||
"extension": (["wav", "flac"],),
|
||||
"filename": ("STRING", {"default": "audio"}),
|
||||
}
|
||||
}
|
||||
|
||||
@@ -109,35 +207,25 @@ class SaveAudioNode:
|
||||
OUTPUT_NODE = True
|
||||
|
||||
def save_audio(self, waveforms, sample_rate, extension, filename):
|
||||
# Build the base audio path
|
||||
base_path = Path(output_directory) / filename
|
||||
|
||||
# Initialize a counter
|
||||
counter = 1
|
||||
|
||||
# Check if the file exists and append a number if it does
|
||||
while True:
|
||||
# Format the filename with leading zeros for numbering
|
||||
if counter == 1:
|
||||
audio_path = base_path.with_suffix(f".{extension}") # First instance
|
||||
else:
|
||||
audio_path = base_path.with_name(f"{filename}_{counter:05d}").with_suffix(f".{extension}")
|
||||
|
||||
if not audio_path.exists():
|
||||
break # Found a unique filename
|
||||
|
||||
counter += 1 # Increment the counter
|
||||
|
||||
# Save the audio file
|
||||
sf.write(audio_path.as_posix(), waveforms, sample_rate)
|
||||
|
||||
soundfile = require_module("soundfile")
|
||||
safe_name = Path(filename).name.strip() or "audio"
|
||||
output = Path(folder_paths.output_directory)
|
||||
output.mkdir(parents=True, exist_ok=True)
|
||||
base = output / safe_name
|
||||
path = base.with_suffix(f".{extension}")
|
||||
counter = 2
|
||||
while path.exists():
|
||||
path = output / f"{safe_name}_{counter:05d}.{extension}"
|
||||
counter += 1
|
||||
soundfile.write(path, np.asarray(waveforms), int(sample_rate))
|
||||
return ()
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"AudioLDM2Node": AudioLDM2Node,
|
||||
"SaveAudioNode": SaveAudioNode
|
||||
"SaveAudioNode": SaveAudioNode,
|
||||
}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"AudioLDM2Node": "AudioLDM-2 Node",
|
||||
"SaveAudioNode": "Save Audio Node"
|
||||
"AudioLDM2Node": "AudioLDM2",
|
||||
"SaveAudioNode": "Save Audio",
|
||||
}
|
||||
|
||||
@@ -0,0 +1,35 @@
|
||||
"""A zero-download runtime report for portable support requests."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
|
||||
from .runtime import runtime_diagnostics
|
||||
|
||||
|
||||
class VLMRuntimeDiagnostics:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {"required": {}}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
RETURN_NAMES = ("runtime_report",)
|
||||
FUNCTION = "report"
|
||||
CATEGORY = "VLM Nodes/Diagnostics"
|
||||
OUTPUT_NODE = True
|
||||
|
||||
def report(self):
|
||||
return (
|
||||
json.dumps(
|
||||
runtime_diagnostics(),
|
||||
ensure_ascii=False,
|
||||
indent=2,
|
||||
sort_keys=True,
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"VLMRuntimeDiagnostics": VLMRuntimeDiagnostics}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"VLMRuntimeDiagnostics": "VLM Runtime Diagnostics"
|
||||
}
|
||||
@@ -0,0 +1,208 @@
|
||||
"""Florence-2 multitask caption, OCR, detection and segmentation node."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
|
||||
import torch
|
||||
from PIL import Image, ImageDraw
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
inference_context,
|
||||
model_device,
|
||||
move_inputs,
|
||||
pil_mask_to_tensor,
|
||||
pil_to_tensor,
|
||||
require_module,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
MODELS = {
|
||||
"Florence-2 base FT (fast)": "florence-community/Florence-2-base-ft",
|
||||
"Florence-2 large FT (recommended)": (
|
||||
"florence-community/Florence-2-large-ft"
|
||||
),
|
||||
}
|
||||
TASKS = {
|
||||
"Caption": "<CAPTION>",
|
||||
"Detailed caption": "<DETAILED_CAPTION>",
|
||||
"More detailed caption": "<MORE_DETAILED_CAPTION>",
|
||||
"OCR": "<OCR>",
|
||||
"OCR with regions": "<OCR_WITH_REGION>",
|
||||
"Object detection": "<OD>",
|
||||
"Dense region caption": "<DENSE_REGION_CAPTION>",
|
||||
"Region proposals": "<REGION_PROPOSAL>",
|
||||
"Referring expression segmentation": "<REFERRING_EXPRESSION_SEGMENTATION>",
|
||||
"Open vocabulary detection": "<OPEN_VOCABULARY_DETECTION>",
|
||||
}
|
||||
|
||||
|
||||
class FlorencePredictor:
|
||||
def __init__(self, model_label):
|
||||
transformers = require_module("transformers")
|
||||
repo_id = MODELS[model_label]
|
||||
path = snapshot_download(
|
||||
repo_id,
|
||||
f"florence2/{repo_id.replace('/', '--')}",
|
||||
ignore_patterns=["*.bin"],
|
||||
)
|
||||
self.dtype = torch_dtype("float16")
|
||||
self.processor = transformers.Florence2Processor.from_pretrained(path)
|
||||
model = transformers.Florence2ForConditionalGeneration.from_pretrained(
|
||||
path,
|
||||
dtype=self.dtype,
|
||||
)
|
||||
model.eval()
|
||||
self.handle = ManagedTorchModel(model, processor=self.processor)
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
def run(self, image, task_token, text, max_new_tokens, beams):
|
||||
prompt = task_token + (text.strip() if text.strip() else "")
|
||||
inputs = self.processor(
|
||||
text=prompt, images=image, return_tensors="pt"
|
||||
)
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
inputs = move_inputs(inputs, device, floating_dtype=self.dtype)
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
generated = model.generate(
|
||||
**inputs,
|
||||
max_new_tokens=int(max_new_tokens),
|
||||
num_beams=int(beams),
|
||||
do_sample=False,
|
||||
early_stopping=int(beams) > 1,
|
||||
)
|
||||
raw = self.processor.batch_decode(
|
||||
generated, skip_special_tokens=False
|
||||
)[0]
|
||||
parsed = self.processor.post_process_generation(
|
||||
raw, task=task_token, image_size=image.size
|
||||
)
|
||||
return raw, parsed
|
||||
|
||||
|
||||
def _json_default(value):
|
||||
if hasattr(value, "tolist"):
|
||||
return value.tolist()
|
||||
return str(value)
|
||||
|
||||
|
||||
def _visualize(image, parsed):
|
||||
result = next(iter(parsed.values()), parsed) if isinstance(parsed, dict) else {}
|
||||
mask = Image.new("L", image.size, 0)
|
||||
visual = image.copy().convert("RGB")
|
||||
mask_draw = ImageDraw.Draw(mask)
|
||||
draw = ImageDraw.Draw(visual)
|
||||
labels = result.get("labels", []) if isinstance(result, dict) else []
|
||||
|
||||
for index, box in enumerate(result.get("bboxes", [])):
|
||||
box = [float(value) for value in box]
|
||||
draw.rectangle(box, outline="#00ff88", width=3)
|
||||
if index < len(labels):
|
||||
draw.text((box[0] + 3, box[1] + 3), str(labels[index]), fill="#00ff88")
|
||||
|
||||
for quad in result.get("quad_boxes", []):
|
||||
points = [
|
||||
(float(quad[index]), float(quad[index + 1]))
|
||||
for index in range(0, len(quad), 2)
|
||||
]
|
||||
draw.line(points + [points[0]], fill="#00c8ff", width=3)
|
||||
|
||||
polygons = result.get("polygons", [])
|
||||
for group in polygons:
|
||||
# Florence may return either one flat polygon or a list of polygons.
|
||||
groups = [group] if group and isinstance(group[0], (int, float)) else group
|
||||
for polygon in groups:
|
||||
points = [
|
||||
(float(polygon[index]), float(polygon[index + 1]))
|
||||
for index in range(0, len(polygon), 2)
|
||||
]
|
||||
if len(points) >= 3:
|
||||
mask_draw.polygon(points, fill=255)
|
||||
draw.line(points + [points[0]], fill="#ff4da6", width=3)
|
||||
return mask, visual
|
||||
|
||||
|
||||
class Florence2(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"task": (list(TASKS),),
|
||||
"text_input": (
|
||||
"STRING",
|
||||
{
|
||||
"default": "",
|
||||
"multiline": True,
|
||||
"tooltip": "Required for referring-expression and open-vocabulary tasks.",
|
||||
},
|
||||
),
|
||||
"model": (
|
||||
list(MODELS),
|
||||
{"default": "Florence-2 large FT (recommended)"},
|
||||
),
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 1024, "min": 1, "max": 4096},
|
||||
),
|
||||
"beams": ("INT", {"default": 3, "min": 1, "max": 8}),
|
||||
},
|
||||
"optional": {
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING", "STRING", "MASK", "IMAGE")
|
||||
RETURN_NAMES = ("text", "structured_json", "mask", "visualization")
|
||||
FUNCTION = "run"
|
||||
CATEGORY = "VLM Nodes/Florence-2"
|
||||
|
||||
def run(
|
||||
self,
|
||||
image,
|
||||
task,
|
||||
text_input,
|
||||
model,
|
||||
max_new_tokens,
|
||||
beams,
|
||||
unload_after=False,
|
||||
):
|
||||
predictor = self.get_or_create_model(
|
||||
model, lambda: FlorencePredictor(model)
|
||||
)
|
||||
texts, records, masks, visuals = [], [], [], []
|
||||
try:
|
||||
for pil_image in tensor_batch_to_pil(image):
|
||||
raw, parsed = predictor.run(
|
||||
pil_image,
|
||||
TASKS[task],
|
||||
text_input,
|
||||
max_new_tokens,
|
||||
beams,
|
||||
)
|
||||
texts.append(raw)
|
||||
records.append(parsed)
|
||||
mask, visual = _visualize(pil_image, parsed)
|
||||
masks.append(pil_mask_to_tensor(mask))
|
||||
visuals.append(pil_to_tensor(visual))
|
||||
return (
|
||||
batch_text(texts),
|
||||
json.dumps(records, ensure_ascii=False, default=_json_default),
|
||||
torch.cat(masks),
|
||||
torch.cat(visuals),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"Florence2": Florence2}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Florence2": "Florence-2 Multitask Vision"}
|
||||
+120
-121
@@ -1,141 +1,140 @@
|
||||
from .joytagger import Models
|
||||
from PIL import Image
|
||||
import torch.amp.autocast_mode
|
||||
from pathlib import Path
|
||||
"""JoyTag image tagging with cached, ComfyUI-managed model weights."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchvision.transforms.functional as TVF
|
||||
from huggingface_hub import snapshot_download
|
||||
from torchvision import transforms
|
||||
import folder_paths
|
||||
from PIL import Image
|
||||
|
||||
THRESHOLD = 0.4
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
inference_context,
|
||||
model_device,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
# Define your local directory where you want to save the files
|
||||
files_for_joytagger = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for_joytagger"
|
||||
|
||||
# Check if the directory exists, create if it doesn't (optional)
|
||||
files_for_joytagger.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
def download_joytag():
|
||||
# Ensure the correct behavior based on the existence of the local directory
|
||||
print(f"Target directory for download: {files_for_joytagger}")
|
||||
|
||||
# Call snapshot_download with specified parameters
|
||||
path = snapshot_download(
|
||||
"fancyfeast/joytag", # Example repo_id
|
||||
local_dir=files_for_joytagger,
|
||||
force_download=False, # Set to True if you always want to download, regardless of local copy
|
||||
local_files_only=False, # Set to False to allow downloading if not available locally
|
||||
local_dir_use_symlinks="auto" # or set to True/False based on your symlink preference
|
||||
)
|
||||
print(f"Model path: {path}")
|
||||
return path
|
||||
MODEL_ID = "fancyfeast/joytag"
|
||||
|
||||
|
||||
def prepare_image(image: Image.Image, target_size: int) -> torch.Tensor:
|
||||
# Pad image to square
|
||||
image_shape = image.size
|
||||
max_dim = max(image_shape)
|
||||
pad_left = (max_dim - image_shape[0]) // 2
|
||||
pad_top = (max_dim - image_shape[1]) // 2
|
||||
|
||||
padded_image = Image.new('RGB', (max_dim, max_dim), (255, 255, 255))
|
||||
padded_image.paste(image, (pad_left, pad_top))
|
||||
|
||||
# Resize image
|
||||
if max_dim != target_size:
|
||||
padded_image = padded_image.resize((target_size, target_size), Image.BICUBIC)
|
||||
|
||||
# Convert to tensor
|
||||
image_tensor = TVF.pil_to_tensor(padded_image) / 255.0
|
||||
|
||||
# Normalize
|
||||
image_tensor = TVF.normalize(image_tensor, mean=[0.48145466, 0.4578275, 0.40821073], std=[0.26862954, 0.26130258, 0.27577711])
|
||||
|
||||
return image_tensor
|
||||
width, height = image.size
|
||||
side = max(width, height)
|
||||
canvas = Image.new("RGB", (side, side), (255, 255, 255))
|
||||
canvas.paste(image.convert("RGB"), ((side - width) // 2, (side - height) // 2))
|
||||
if side != target_size:
|
||||
canvas = canvas.resize(
|
||||
(target_size, target_size), Image.Resampling.BICUBIC
|
||||
)
|
||||
array = np.asarray(canvas, dtype=np.float32) / 255.0
|
||||
tensor = torch.from_numpy(array.copy()).permute(2, 0, 1)
|
||||
mean = torch.tensor([0.48145466, 0.4578275, 0.40821073])[:, None, None]
|
||||
std = torch.tensor([0.26862954, 0.26130258, 0.27577711])[:, None, None]
|
||||
return (tensor - mean) / std
|
||||
|
||||
|
||||
def clean_tag(tag: str) -> str:
|
||||
return (
|
||||
tag.replace("(medium)", "")
|
||||
.replace("\\", "")
|
||||
.replace("m/", "")
|
||||
.replace("_", " ")
|
||||
.strip(" -")
|
||||
)
|
||||
|
||||
|
||||
# Extract and process the tags
|
||||
def process_tag(tag):
|
||||
tag = tag.replace("(medium)", "") # Remove (medium)
|
||||
tag = tag.replace("\\", "") # Remove \
|
||||
tag = tag.replace("m/", "") # Remove m/
|
||||
tag = tag.replace("-", "") # Remove -
|
||||
tag = tag.replace("_", " ") # Replace underscores with spaces
|
||||
tag = tag.strip() # Remove leading and trailing spaces
|
||||
return tag
|
||||
class JoyTagPredictor:
|
||||
def __init__(self):
|
||||
from .joytagger import Models
|
||||
|
||||
class Joytag:
|
||||
def __init__(self):
|
||||
pass
|
||||
path = snapshot_download(MODEL_ID, "joytag")
|
||||
model = Models.VisionModel.load_model(path, device=None).eval()
|
||||
self.tags = [
|
||||
line.strip()
|
||||
for line in (path / "top_tags.txt").read_text(
|
||||
encoding="utf-8"
|
||||
).splitlines()
|
||||
if line.strip()
|
||||
]
|
||||
self.dtype = torch_dtype("float16")
|
||||
self.handle = ManagedTorchModel(model)
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"tag_number": ("INT", {
|
||||
"default": 1,
|
||||
"min": 1, #Minimum value
|
||||
"max": 100, #Maximum value
|
||||
"step": 1, #Slider's step
|
||||
"display": "number" # Cosmetic only: display as "number" or "slider"
|
||||
}),
|
||||
},
|
||||
}
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.tags = []
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
def predict(self, images, count: int, threshold: float):
|
||||
results = []
|
||||
for image in tensor_batch_to_pil(images):
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
tensor = prepare_image(image, model.image_size).unsqueeze(0).to(device)
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
predictions = model({"image": tensor})["tags"].sigmoid()[0]
|
||||
scores = predictions.float().cpu()
|
||||
ranked = torch.argsort(scores, descending=True).tolist()
|
||||
selected = [
|
||||
index
|
||||
for index in ranked
|
||||
if scores[index].item() >= float(threshold)
|
||||
][: int(count)]
|
||||
# Always return up to tag_number useful results, even when the
|
||||
# threshold is deliberately high.
|
||||
if not selected:
|
||||
selected = ranked[: int(count)]
|
||||
tags = [clean_tag(self.tags[index]) for index in selected]
|
||||
results.append(", ".join(tag for tag in tags if tag))
|
||||
return batch_text(results)
|
||||
|
||||
FUNCTION = "tags"
|
||||
|
||||
CATEGORY = "VLM Nodes/JoyTag"
|
||||
class Joytag(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"tag_number": (
|
||||
"INT",
|
||||
{
|
||||
"default": 20,
|
||||
"min": 1,
|
||||
"max": 100,
|
||||
"step": 1,
|
||||
"display": "number",
|
||||
},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"threshold": (
|
||||
"FLOAT",
|
||||
{"default": 0.4, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
def tags(self, image, tag_number):
|
||||
path = download_joytag()
|
||||
print(f"Model path: {path}")
|
||||
model = Models.VisionModel.load_model(Path(path), device='cuda')
|
||||
model.eval()
|
||||
with open(Path(path) / 'top_tags.txt', 'r') as f:
|
||||
top_tags = [line.strip() for line in f.readlines() if line.strip()]
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "tags"
|
||||
CATEGORY = "VLM Nodes/JoyTag"
|
||||
|
||||
@torch.no_grad()
|
||||
def predict(image: Image.Image):
|
||||
image_tensor = prepare_image(image, model.image_size)
|
||||
batch = {
|
||||
'image': image_tensor.unsqueeze(0).to('cuda'),
|
||||
}
|
||||
|
||||
with torch.amp.autocast_mode.autocast('cuda', enabled=True):
|
||||
preds = model(batch)
|
||||
tag_preds = preds['tags'].sigmoid().cpu()
|
||||
|
||||
scores = {top_tags[i]: tag_preds[0][i] for i in range(len(top_tags))}
|
||||
predicted_tags = [tag for tag, score in scores.items() if score > THRESHOLD]
|
||||
tag_string = ', '.join(predicted_tags)
|
||||
|
||||
return tag_string, scores
|
||||
|
||||
image = transforms.ToPILImage()(image[0].permute(2, 0, 1))
|
||||
_, scores = predict(image)
|
||||
|
||||
# Get the top 50 tag and score pairs
|
||||
top_tags_scores = sorted(scores.items(), key=lambda x: x[1], reverse=True)[:tag_number]
|
||||
|
||||
# Extract the tags from the pairs
|
||||
top_tags_processed = [process_tag(tag) for tag, _ in top_tags_scores]
|
||||
|
||||
top_tags_full = [tag for tag in top_tags_processed if tag]
|
||||
|
||||
# Concatenate the tags with a comma separator
|
||||
top_50_tags_string = ', '.join(top_tags_full)
|
||||
|
||||
return (top_50_tags_string, )
|
||||
def tags(
|
||||
self,
|
||||
image,
|
||||
tag_number,
|
||||
threshold=0.4,
|
||||
unload_after=False,
|
||||
):
|
||||
predictor = self.get_or_create_model(MODEL_ID, JoyTagPredictor)
|
||||
try:
|
||||
return (
|
||||
predictor.predict(image, tag_number, threshold),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
# A dictionary that contains all nodes you want to export with their names
|
||||
NODE_CLASS_MAPPINGS = {"Joytag": Joytag}
|
||||
|
||||
# A dictionary that contains the friendly/humanly readable titles for the nodes
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Joytag": "Joytag Node"}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Joytag": "JoyTag"}
|
||||
|
||||
@@ -2,7 +2,6 @@ import json
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
import torch
|
||||
import torch.backends.cuda
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
import torchvision
|
||||
@@ -211,9 +210,8 @@ class FastCLIPAttention2(nn.Module):
|
||||
v_states = v_states.view(bsz, src_len, self.num_heads, self.head_dim).transpose(1, 2) # (bsz, num_heads, src_len, head_dim)
|
||||
|
||||
# Performs scale of query_states, attention, and softmax
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False):
|
||||
x = F.scaled_dot_product_attention(q_states, k_states, v_states) # (bsz, num_heads, tgt_len, head_dim)
|
||||
x = x.transpose(1, 2).contiguous().view(bsz, tgt_len, embed_dim) # (bsz, tgt_len, embed_dim)
|
||||
x = F.scaled_dot_product_attention(q_states, k_states, v_states) # (bsz, num_heads, tgt_len, head_dim)
|
||||
x = x.transpose(1, 2).contiguous().view(bsz, tgt_len, embed_dim) # (bsz, tgt_len, embed_dim)
|
||||
|
||||
# Projection
|
||||
x = self.out_proj(x) # (bsz, tgt_len, out_dim)
|
||||
@@ -865,9 +863,8 @@ class ViTBlock(nn.Module):
|
||||
k_states = qkv_states[1].view(bsz, src_len, self.num_heads, embed_dim // self.num_heads).transpose(1, 2) # (bsz, num_heads, src_len, embed_dim // num_heads)
|
||||
v_states = qkv_states[2].view(bsz, src_len, self.num_heads, embed_dim // self.num_heads).transpose(1, 2) # (bsz, num_heads, src_len, embed_dim // num_heads)
|
||||
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False):
|
||||
out = F.scaled_dot_product_attention(q_states, k_states, v_states) # (bsz, num_heads, tgt_len, head_dim)
|
||||
out = out.transpose(1, 2).contiguous().view(bsz, src_len, embed_dim) # (bsz, tgt_len, embed_dim)
|
||||
out = F.scaled_dot_product_attention(q_states, k_states, v_states) # (bsz, num_heads, tgt_len, head_dim)
|
||||
out = out.transpose(1, 2).contiguous().view(bsz, src_len, embed_dim) # (bsz, tgt_len, embed_dim)
|
||||
|
||||
out = self.out_proj(out)
|
||||
|
||||
|
||||
+98
-61
@@ -1,59 +1,84 @@
|
||||
from transformers import AutoModelForVision2Seq, AutoProcessor
|
||||
from PIL import Image
|
||||
from pathlib import Path
|
||||
"""Kosmos-2 grounding/caption node with lazy, Comfy-managed loading."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import torch
|
||||
from torchvision.transforms import ToPILImage
|
||||
from huggingface_hub import snapshot_download
|
||||
import folder_paths
|
||||
# Define the directory for saving files related to your new model
|
||||
files_for_new_model = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for_kosmos2"
|
||||
files_for_new_model.mkdir(parents=True, exist_ok=True) # Ensure the directory exists
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
inference_context,
|
||||
model_device,
|
||||
move_inputs,
|
||||
require_module,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
MODEL_ID = "microsoft/kosmos-2-patch14-224"
|
||||
|
||||
|
||||
class KosmosModelPredictor:
|
||||
def __init__(self):
|
||||
self.model_path = snapshot_download("microsoft/kosmos-2-patch14-224",
|
||||
local_dir=files_for_new_model,
|
||||
force_download=False, # Set to True if you always want to download, regardless of local copy
|
||||
local_files_only=False, # Set to False to allow downloading if not available locally
|
||||
local_dir_use_symlinks="auto",
|
||||
ignore_patterns=["*.bin", "*.jpg", "*.png"]) # or set to True/False based on your symlink preference
|
||||
self.device = "cuda:0" if torch.cuda.is_available() else "cpu"
|
||||
self.model = AutoModelForVision2Seq.from_pretrained(self.model_path).to(self.device)
|
||||
self.processor = AutoProcessor.from_pretrained(self.model_path)
|
||||
|
||||
def generate_predictions(self, image_path, main_text):
|
||||
# Load the image
|
||||
image_input = Image.open(image_path).convert("RGB")
|
||||
|
||||
text_input = f"<grounding>{main_text}: "
|
||||
|
||||
# Process the inputs
|
||||
inputs = self.processor(text=text_input, images=image_input, return_tensors="pt").to(self.device)
|
||||
|
||||
# Generate predictions
|
||||
generated_ids = self.model.generate(
|
||||
pixel_values=inputs["pixel_values"],
|
||||
input_ids=inputs["input_ids"],
|
||||
attention_mask=inputs["attention_mask"],
|
||||
image_embeds=None,
|
||||
image_embeds_position_mask=inputs["image_embeds_position_mask"],
|
||||
use_cache=True,
|
||||
max_new_tokens=128,
|
||||
transformers = require_module("transformers")
|
||||
model_path = snapshot_download(
|
||||
MODEL_ID, "kosmos2", ignore_patterns=["*.bin"]
|
||||
)
|
||||
self.dtype = torch_dtype("bfloat16")
|
||||
model_class = getattr(
|
||||
transformers,
|
||||
"Kosmos2ForConditionalGeneration",
|
||||
getattr(transformers, "AutoModelForImageTextToText", None),
|
||||
)
|
||||
if model_class is None:
|
||||
raise RuntimeError(
|
||||
"This Transformers version does not include Kosmos-2 support."
|
||||
)
|
||||
model = model_class.from_pretrained(
|
||||
model_path, torch_dtype=self.dtype
|
||||
).eval()
|
||||
self.processor = transformers.AutoProcessor.from_pretrained(model_path)
|
||||
self.handle = ManagedTorchModel(model, processor=self.processor)
|
||||
|
||||
# Decode the generated IDs
|
||||
generated_text = self.processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
# By default, the generated text is cleanup and the entities are extracted.
|
||||
processed_text, entities = self.processor.post_process_generation(generated_text)
|
||||
def generate(self, images, text, max_new_tokens):
|
||||
results = []
|
||||
for image in tensor_batch_to_pil(images):
|
||||
prompt = f"<grounding>{text.strip()}"
|
||||
inputs = self.processor(
|
||||
text=prompt, images=image, return_tensors="pt"
|
||||
)
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
inputs = move_inputs(inputs, device)
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
output = model.generate(
|
||||
**inputs,
|
||||
use_cache=True,
|
||||
max_new_tokens=int(max_new_tokens),
|
||||
)
|
||||
decoded = self.processor.batch_decode(
|
||||
output, skip_special_tokens=True
|
||||
)[0]
|
||||
post_process = getattr(
|
||||
self.processor, "post_process_generation", None
|
||||
)
|
||||
if callable(post_process):
|
||||
processed, _entities = post_process(decoded)
|
||||
else:
|
||||
processed = decoded
|
||||
if processed.startswith(text):
|
||||
processed = processed[len(text) :].lstrip(": \n")
|
||||
results.append(processed.strip())
|
||||
return batch_text(results)
|
||||
|
||||
return processed_text[len(main_text)+2:]
|
||||
|
||||
# Example of integrating NewModelPredictor into a node-like structure
|
||||
class Kosmos2model:
|
||||
def __init__(self):
|
||||
self.predictor = KosmosModelPredictor()
|
||||
|
||||
class Kosmos2model(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
@@ -61,27 +86,39 @@ class Kosmos2model:
|
||||
"image": ("IMAGE",),
|
||||
"text_input": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "",
|
||||
},
|
||||
{"multiline": True, "default": "Describe the image."},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 128, "min": 1, "max": 2048},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
|
||||
FUNCTION = "new_model_generate_predictions"
|
||||
|
||||
CATEGORY = "VLM Nodes/Kosmos-2"
|
||||
|
||||
def new_model_generate_predictions(self, image, text_input):
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
temp_path = files_for_new_model / "temp_image.png"
|
||||
pil_image.save(temp_path)
|
||||
|
||||
response = self.predictor.generate_predictions(temp_path, text_input)
|
||||
return (response, )
|
||||
def new_model_generate_predictions(
|
||||
self,
|
||||
image,
|
||||
text_input,
|
||||
max_new_tokens=128,
|
||||
unload_after=False,
|
||||
):
|
||||
predictor = self.get_or_create_model(
|
||||
MODEL_ID, KosmosModelPredictor
|
||||
)
|
||||
try:
|
||||
return (
|
||||
predictor.generate(image, text_input, max_new_tokens),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"Kosmos2model": Kosmos2model}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Kosmos2model": "Kosmos-2 Node"}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Kosmos2model": "Kosmos-2"}
|
||||
|
||||
+419
-296
@@ -1,76 +1,164 @@
|
||||
"""llama.cpp multimodal nodes with lazy loading and owned GPU cleanup."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Any
|
||||
|
||||
import folder_paths
|
||||
import os
|
||||
from io import BytesIO
|
||||
from llama_cpp import Llama
|
||||
from llama_cpp.llama_chat_format import Llava15ChatHandler
|
||||
import base64
|
||||
from torchvision.transforms import ToPILImage
|
||||
import gc
|
||||
import torch
|
||||
|
||||
from .runtime import (
|
||||
LlamaHandle,
|
||||
LlavaClipConfig,
|
||||
batch_text,
|
||||
close_handle,
|
||||
image_data_uri,
|
||||
resolve_model_path,
|
||||
tensor_batch_to_pil,
|
||||
unwrap_llm,
|
||||
)
|
||||
|
||||
|
||||
supported_LLava_extensions = set(['.gguf'])
|
||||
def _clip_factory(clip: Any):
|
||||
if isinstance(clip, LlavaClipConfig):
|
||||
return clip.create
|
||||
if callable(getattr(clip, "create", None)):
|
||||
return clip.create
|
||||
# Compatibility with workflows that pass a pre-created llama.cpp handler.
|
||||
return lambda: clip
|
||||
|
||||
|
||||
def _make_handle(
|
||||
ckpt_name: str,
|
||||
max_ctx: int,
|
||||
gpu_layers: int,
|
||||
n_threads: int,
|
||||
clip: Any,
|
||||
*,
|
||||
seed: int = 42,
|
||||
) -> LlamaHandle:
|
||||
return LlamaHandle(
|
||||
resolve_model_path(ckpt_name),
|
||||
n_ctx=max_ctx,
|
||||
n_gpu_layers=gpu_layers,
|
||||
n_threads=n_threads,
|
||||
chat_handler_factory=_clip_factory(clip),
|
||||
seed=seed,
|
||||
)
|
||||
|
||||
|
||||
def _vision_messages(system_msg: str, prompt: str, data_uri: str):
|
||||
return [
|
||||
{"role": "system", "content": system_msg},
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "image_url", "image_url": {"url": data_uri}},
|
||||
{"type": "text", "text": prompt},
|
||||
],
|
||||
},
|
||||
]
|
||||
|
||||
|
||||
def _content(response: dict[str, Any]) -> str:
|
||||
try:
|
||||
return str(response["choices"][0]["message"]["content"])
|
||||
except (KeyError, IndexError, TypeError) as exc:
|
||||
raise RuntimeError(f"llama.cpp returned an unexpected response: {response!r}") from exc
|
||||
|
||||
|
||||
def _run_batch(
|
||||
image,
|
||||
model,
|
||||
*,
|
||||
system_msg: str,
|
||||
prompt: str,
|
||||
**generation: Any,
|
||||
) -> str:
|
||||
llm = unwrap_llm(model)
|
||||
responses = []
|
||||
for pil_image in tensor_batch_to_pil(image):
|
||||
response = llm.create_chat_completion(
|
||||
messages=_vision_messages(
|
||||
system_msg, prompt, image_data_uri(pil_image)
|
||||
),
|
||||
**generation,
|
||||
)
|
||||
responses.append(_content(response))
|
||||
return batch_text(responses)
|
||||
|
||||
|
||||
try:
|
||||
folder_paths.folder_names_and_paths["LLavacheckpoints"] = (folder_paths.folder_names_and_paths["LLavacheckpoints"][0], supported_LLava_extensions)
|
||||
except:
|
||||
# check if LLavacheckpoints exists otherwise create
|
||||
if not os.path.isdir(os.path.join(folder_paths.models_dir, "LLavacheckpoints")):
|
||||
os.mkdir(os.path.join(folder_paths.models_dir, "LLavacheckpoints"))
|
||||
|
||||
folder_paths.folder_names_and_paths["LLavacheckpoints"] = ([os.path.join(folder_paths.models_dir, "LLavacheckpoints")], supported_LLava_extensions)
|
||||
|
||||
class LLavaLoader:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {"required": {
|
||||
"ckpt_name": (folder_paths.get_filename_list("LLavacheckpoints"), ),
|
||||
"max_ctx": ("INT", {"default": 4096, "min": 128, "max": 8192, "step": 64}),
|
||||
"gpu_layers": ("INT", {"default": 27, "min": 0, "max": 100, "step": 1}),
|
||||
"n_threads": ("INT", {"default": 8, "min": 1, "max": 100, "step": 1}),
|
||||
"clip": ("CUSTOM", {"default": ""}),
|
||||
}}
|
||||
|
||||
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"ckpt_name": (
|
||||
folder_paths.get_filename_list("LLavacheckpoints"),
|
||||
),
|
||||
"max_ctx": (
|
||||
"INT",
|
||||
{"default": 4096, "min": 128, "max": 131072, "step": 64},
|
||||
),
|
||||
"gpu_layers": (
|
||||
"INT",
|
||||
{"default": 27, "min": -1, "max": 1000, "step": 1},
|
||||
),
|
||||
"n_threads": (
|
||||
"INT",
|
||||
{"default": 8, "min": 1, "max": 256, "step": 1},
|
||||
),
|
||||
"clip": ("CUSTOM", {"default": ""}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("CUSTOM",)
|
||||
RETURN_NAMES = ("model",)
|
||||
FUNCTION = "load_llava_checkpoint"
|
||||
|
||||
CATEGORY = "VLM Nodes/LLava"
|
||||
def load_llava_checkpoint(self, ckpt_name, max_ctx, gpu_layers, n_threads, clip ):
|
||||
ckpt_path = folder_paths.get_full_path("LLavacheckpoints", ckpt_name)
|
||||
llm = Llama(model_path = ckpt_path, chat_handler=clip,offload_kqv=True, f16_kv=True, use_mlock=False, embedding=False, n_batch=1024, last_n_tokens_size=1024, verbose=True, seed=42, n_ctx = max_ctx, n_gpu_layers=gpu_layers, n_threads=n_threads, logits_all=True, echo=False)
|
||||
return (llm, )
|
||||
|
||||
|
||||
def load_llava_checkpoint(
|
||||
self, ckpt_name, max_ctx, gpu_layers, n_threads, clip
|
||||
):
|
||||
# The GGUF and mmproj are loaded only when a sampler actually executes.
|
||||
return (
|
||||
_make_handle(
|
||||
ckpt_name, max_ctx, gpu_layers, n_threads, clip
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
class LlavaClipLoader:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {"required": {
|
||||
"clip_name": (folder_paths.get_filename_list("LLavacheckpoints"), ),
|
||||
}}
|
||||
|
||||
RETURN_TYPES = ("CUSTOM", )
|
||||
RETURN_NAMES = ("clip", )
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"clip_name": (
|
||||
folder_paths.get_filename_list("LLavacheckpoints"),
|
||||
)
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("CUSTOM",)
|
||||
RETURN_NAMES = ("clip",)
|
||||
FUNCTION = "load_clip_checkpoint"
|
||||
|
||||
CATEGORY = "VLM Nodes/LLava"
|
||||
def load_clip_checkpoint(self, clip_name):
|
||||
clip_path = folder_paths.get_full_path("LLavacheckpoints", clip_name)
|
||||
clip = Llava15ChatHandler(clip_model_path = clip_path, verbose=False)
|
||||
return (clip, )
|
||||
|
||||
class LLavaSamplerSimple:
|
||||
def __init__(self):
|
||||
pass
|
||||
|
||||
def load_clip_checkpoint(self, clip_name):
|
||||
return (LlavaClipConfig(resolve_model_path(clip_name)),)
|
||||
|
||||
|
||||
class LLavaSamplerSimple:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"prompt": ("STRING",{"forceInput": True} ),
|
||||
"prompt": ("STRING", {"default": "", "multiline": True}),
|
||||
"model": ("CUSTOM", {"default": ""}),
|
||||
"temperature": ("FLOAT", {"default": 0.1, "min": 0.01, "max": 1.0, "step": 0.01}),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.1, "min": 0.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
@@ -79,62 +167,62 @@ class LLavaSamplerSimple:
|
||||
CATEGORY = "VLM Nodes/LLava"
|
||||
|
||||
def generate_text(self, image, prompt, model, temperature):
|
||||
|
||||
|
||||
# Assuming 'image' is a PyTorch tensor of shape [C, H, W]
|
||||
# Convert the PyTorch tensor to a PIL image
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
|
||||
# Convert the PIL image to a bytes buffer
|
||||
buffer = BytesIO()
|
||||
pil_image.save(buffer, format="PNG") # You can change the format if needed
|
||||
|
||||
# Get the bytes from the buffer
|
||||
image_bytes = buffer.getvalue()
|
||||
|
||||
# Encode the bytes to base64
|
||||
base64_string = f"data:image/jpeg;base64,{base64.b64encode(image_bytes).decode('utf-8')}"
|
||||
|
||||
# Now, `base64_string` contains the base64-encoded string of the image
|
||||
|
||||
llm = model
|
||||
response = llm.create_chat_completion(
|
||||
messages = [
|
||||
{"role": "system", "content": "You are an assistant who perfectly describes images."},
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "image_url", "image_url": {"url" : base64_string}},
|
||||
{"type" : "text", "text": f"{prompt}"}
|
||||
]
|
||||
}
|
||||
|
||||
],
|
||||
temperature = temperature,
|
||||
return (
|
||||
_run_batch(
|
||||
image,
|
||||
model,
|
||||
system_msg="You are an assistant who accurately describes images.",
|
||||
prompt=prompt,
|
||||
temperature=temperature,
|
||||
),
|
||||
)
|
||||
|
||||
return (f"{response['choices'][0]['message']['content']}", )
|
||||
|
||||
class LLavaSamplerAdvanced:
|
||||
def __init__(self):
|
||||
pass
|
||||
|
||||
|
||||
class LLavaSamplerAdvanced:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"system_msg": ("STRING",{"default" : "You are an assistant who perfectly describes images."}),
|
||||
"prompt": ("STRING",{"forceInput": True, "default": ""}),
|
||||
"system_msg": (
|
||||
"STRING",
|
||||
{
|
||||
"default": (
|
||||
"You are an assistant who accurately describes images."
|
||||
)
|
||||
},
|
||||
),
|
||||
"prompt": (
|
||||
"STRING",
|
||||
{"default": "", "multiline": True},
|
||||
),
|
||||
"model": ("CUSTOM", {"default": ""}),
|
||||
"max_tokens": ("INT", {"default": 512, "min": 1, "max": 2048, "step": 1}),
|
||||
"temperature": ("FLOAT", {"default": 0.1, "min": 0.01, "max": 1.0, "step": 0.01}),
|
||||
"top_p": ("FLOAT", {"default": 0.95, "min": 0.1, "max": 1.0, "step": 0.01}),
|
||||
"top_k": ("INT", {"default": 40, "step": 1}),
|
||||
"frequency_penalty": ("FLOAT", {"default": 0.0, "step": 0.01}),
|
||||
"presence_penalty": ("FLOAT", {"default": 0.0, "step": 0.01}),
|
||||
"repeat_penalty": ("FLOAT", {"default": 1.1, "step": 0.01}),
|
||||
"seed": ("INT", {"default": 42, "step":1})
|
||||
"max_tokens": (
|
||||
"INT",
|
||||
{"default": 512, "min": 1, "max": 8192, "step": 1},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.1, "min": 0.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.95, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"top_k": ("INT", {"default": 40, "min": 0, "step": 1}),
|
||||
"frequency_penalty": (
|
||||
"FLOAT",
|
||||
{"default": 0.0, "min": -2.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"presence_penalty": (
|
||||
"FLOAT",
|
||||
{"default": 0.0, "min": -2.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"repeat_penalty": (
|
||||
"FLOAT",
|
||||
{"default": 1.1, "min": 0.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"seed": ("INT", {"default": 42, "step": 1}),
|
||||
}
|
||||
}
|
||||
|
||||
@@ -142,69 +230,112 @@ class LLavaSamplerAdvanced:
|
||||
FUNCTION = "generate_text_advanced"
|
||||
CATEGORY = "VLM Nodes/LLava"
|
||||
|
||||
def generate_text_advanced(self, image, system_msg, prompt, model, max_tokens, temperature, top_p, frequency_penalty, presence_penalty, repeat_penalty, top_k,seed):
|
||||
|
||||
# Assuming 'image' is a PyTorch tensor of shape [C, H, W]
|
||||
# Convert the PyTorch tensor to a PIL image
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
|
||||
# Convert the PIL image to a bytes buffer
|
||||
buffer = BytesIO()
|
||||
pil_image.save(buffer, format="PNG") # You can change the format if needed
|
||||
|
||||
# Get the bytes from the buffer
|
||||
image_bytes = buffer.getvalue()
|
||||
|
||||
# Encode the bytes to base64
|
||||
base64_string = f"data:image/jpeg;base64,{base64.b64encode(image_bytes).decode('utf-8')}"
|
||||
|
||||
# Now, `base64_string` contains the base64-encoded string of the image
|
||||
|
||||
llm = model
|
||||
response = llm.create_chat_completion(
|
||||
messages = [
|
||||
{"role": "system", "content": system_msg},
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "image_url", "image_url": {"url" : base64_string}},
|
||||
{"type" : "text", "text": f"{prompt}"}
|
||||
]
|
||||
}
|
||||
|
||||
],
|
||||
max_tokens = max_tokens,
|
||||
temperature = temperature,
|
||||
top_p = top_p,
|
||||
top_k = top_k,
|
||||
frequency_penalty = frequency_penalty,
|
||||
presence_penalty = presence_penalty,
|
||||
repeat_penalty = repeat_penalty,
|
||||
seed=seed
|
||||
|
||||
def generate_text_advanced(
|
||||
self,
|
||||
image,
|
||||
system_msg,
|
||||
prompt,
|
||||
model,
|
||||
max_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
top_k,
|
||||
frequency_penalty,
|
||||
presence_penalty,
|
||||
repeat_penalty,
|
||||
seed,
|
||||
):
|
||||
return (
|
||||
_run_batch(
|
||||
image,
|
||||
model,
|
||||
system_msg=system_msg,
|
||||
prompt=prompt,
|
||||
max_tokens=max_tokens,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
top_k=top_k,
|
||||
frequency_penalty=frequency_penalty,
|
||||
presence_penalty=presence_penalty,
|
||||
repeat_penalty=repeat_penalty,
|
||||
seed=seed,
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
return (f"{response['choices'][0]['message']['content']}", )
|
||||
|
||||
class LLavaOptionalMemoryFreeSimple:
|
||||
class _CachedLlavaBase:
|
||||
def __init__(self):
|
||||
self.llm = None # Store the model instance
|
||||
self.clip = None # Store the clip instance
|
||||
self._handle = None
|
||||
self._key = None
|
||||
|
||||
def _model(
|
||||
self,
|
||||
ckpt_name,
|
||||
clip_name,
|
||||
max_ctx,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
seed=42,
|
||||
):
|
||||
key = (
|
||||
ckpt_name,
|
||||
clip_name,
|
||||
int(max_ctx),
|
||||
int(gpu_layers),
|
||||
int(n_threads),
|
||||
int(seed),
|
||||
)
|
||||
if self._handle is None or self._key != key:
|
||||
close_handle(self._handle)
|
||||
clip = LlavaClipConfig(resolve_model_path(clip_name))
|
||||
self._handle = _make_handle(
|
||||
ckpt_name,
|
||||
max_ctx,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
clip,
|
||||
seed=seed,
|
||||
)
|
||||
self._key = key
|
||||
return self._handle
|
||||
|
||||
def _maybe_unload(self, unload):
|
||||
if unload:
|
||||
close_handle(self._handle)
|
||||
self._handle = None
|
||||
self._key = None
|
||||
|
||||
|
||||
class LLavaOptionalMemoryFreeSimple(_CachedLlavaBase):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"ckpt_name": (folder_paths.get_filename_list("LLavacheckpoints"), ),
|
||||
"clip_name": (folder_paths.get_filename_list("LLavacheckpoints"), ),
|
||||
"max_ctx": ("INT", {"default": 4096, "min": 128, "max": 128000, "step": 64}),
|
||||
"gpu_layers": ("INT", {"default": 27, "min": 0, "max": 100, "step": 1}),
|
||||
"n_threads": ("INT", {"default": 8, "min": 1, "max": 100, "step": 1}),
|
||||
"ckpt_name": (
|
||||
folder_paths.get_filename_list("LLavacheckpoints"),
|
||||
),
|
||||
"clip_name": (
|
||||
folder_paths.get_filename_list("LLavacheckpoints"),
|
||||
),
|
||||
"max_ctx": (
|
||||
"INT",
|
||||
{"default": 4096, "min": 128, "max": 131072, "step": 64},
|
||||
),
|
||||
"gpu_layers": (
|
||||
"INT",
|
||||
{"default": 27, "min": -1, "max": 1000, "step": 1},
|
||||
),
|
||||
"n_threads": (
|
||||
"INT",
|
||||
{"default": 8, "min": 1, "max": 256, "step": 1},
|
||||
),
|
||||
"image": ("IMAGE",),
|
||||
"prompt": ("STRING", {"forceInput": True}),
|
||||
"temperature": ("FLOAT", {"default": 0.1, "min": 0.01, "max": 1.0, "step": 0.01}),
|
||||
"unload": ("BOOLEAN", {"default": False}), # Add unload parameter
|
||||
"prompt": ("STRING", {"default": "", "multiline": True}),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.1, "min": 0.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"unload": ("BOOLEAN", {"default": False}),
|
||||
}
|
||||
}
|
||||
|
||||
@@ -212,155 +343,147 @@ class LLavaOptionalMemoryFreeSimple:
|
||||
FUNCTION = "generate_text"
|
||||
CATEGORY = "VLM Nodes/LLava"
|
||||
|
||||
def generate_text(self, ckpt_name, clip_name, max_ctx, gpu_layers, n_threads, image, prompt, temperature, unload):
|
||||
# Load the model
|
||||
|
||||
|
||||
# Load the clip
|
||||
clip_path = folder_paths.get_full_path("LLavacheckpoints", clip_name)
|
||||
self.clip = Llava15ChatHandler(clip_model_path=clip_path, verbose=False)
|
||||
|
||||
# Load model
|
||||
ckpt_path = folder_paths.get_full_path("LLavacheckpoints", ckpt_name)
|
||||
self.llm = Llama(model_path = ckpt_path, chat_handler=self.clip, offload_kqv=True, f16_kv=True, use_mlock=False, embedding=False, n_batch=1024, last_n_tokens_size=1024, verbose=True, seed=42, n_ctx = max_ctx, n_gpu_layers=gpu_layers, n_threads=n_threads, logits_all=True, echo=False)
|
||||
|
||||
# Assuming 'image' is a PyTorch tensor of shape [C, H, W]
|
||||
# Convert the PyTorch tensor to a PIL image
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
|
||||
# Convert the PIL image to a bytes buffer
|
||||
buffer = BytesIO()
|
||||
pil_image.save(buffer, format="PNG") # You can change the format if needed
|
||||
|
||||
# Get the bytes from the buffer
|
||||
image_bytes = buffer.getvalue()
|
||||
|
||||
# Encode the bytes to base64
|
||||
base64_string = f"data:image/jpeg;base64,{base64.b64encode(image_bytes).decode('utf-8')}"
|
||||
|
||||
# Now, `base64_string` contains the base64-encoded string of the image
|
||||
|
||||
response = self.llm.create_chat_completion(
|
||||
messages=[
|
||||
{"role": "system", "content": "You are an assistant who perfectly describes images."},
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "image_url", "image_url": {"url": base64_string}},
|
||||
{"type": "text", "text": f"{prompt}"}
|
||||
]
|
||||
}
|
||||
],
|
||||
temperature=temperature,
|
||||
def generate_text(
|
||||
self,
|
||||
ckpt_name,
|
||||
clip_name,
|
||||
max_ctx,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
image,
|
||||
prompt,
|
||||
temperature,
|
||||
unload,
|
||||
):
|
||||
model = self._model(
|
||||
ckpt_name, clip_name, max_ctx, gpu_layers, n_threads
|
||||
)
|
||||
try:
|
||||
result = _run_batch(
|
||||
image,
|
||||
model,
|
||||
system_msg="You are an assistant who accurately describes images.",
|
||||
prompt=prompt,
|
||||
temperature=temperature,
|
||||
)
|
||||
return (result,)
|
||||
finally:
|
||||
self._maybe_unload(unload)
|
||||
|
||||
if unload and self.llm is not None:
|
||||
del self.llm # Unload the model
|
||||
self.llm = None # Remove reference to the model
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
if unload and self.clip is not None:
|
||||
del self.clip # Unload the clip
|
||||
self.clip = None # Remove reference to the clip
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
return (f"{response['choices'][0]['message']['content']}", )
|
||||
|
||||
class LLavaOptionalMemoryFreeAdvanced:
|
||||
def __init__(self):
|
||||
self.llm = None # Store the model instance
|
||||
self.clip = None # Store the clip instance
|
||||
|
||||
class LLavaOptionalMemoryFreeAdvanced(_CachedLlavaBase):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"ckpt_name": (folder_paths.get_filename_list("LLavacheckpoints"), ),
|
||||
"clip_name": (folder_paths.get_filename_list("LLavacheckpoints"), ),
|
||||
"max_ctx": ("INT", {"default": 4096, "min": 128, "max": 128000, "step": 64}),
|
||||
"gpu_layers": ("INT", {"default": 27, "min": 0, "max": 100, "step": 1}),
|
||||
"n_threads": ("INT", {"default": 8, "min": 1, "max": 100, "step": 1}),
|
||||
"image": ("IMAGE",),
|
||||
"system_msg": ("STRING", {"default": "You are an assistant who perfectly describes images."}),
|
||||
"prompt": ("STRING", {"forceInput": True, "default": ""}),
|
||||
"max_tokens": ("INT", {"default": 512, "min": 1, "max": 2048, "step": 1}),
|
||||
"temperature": ("FLOAT", {"default": 0.1, "min": 0.01, "max": 1.0, "step": 0.01}),
|
||||
"top_p": ("FLOAT", {"default": 0.95, "min": 0.1, "max": 1.0, "step": 0.01}),
|
||||
"top_k": ("INT", {"default": 40, "step": 1}),
|
||||
"frequency_penalty": ("FLOAT", {"default": 0.0, "step": 0.01}),
|
||||
"presence_penalty": ("FLOAT", {"default": 0.0, "step": 0.01}),
|
||||
"repeat_penalty": ("FLOAT", {"default": 1.1, "step": 0.01}),
|
||||
"seed": ("INT", {"default": 42, "step": 1}),
|
||||
"unload": ("BOOLEAN", {"default": False}), # Add unload parameter
|
||||
}
|
||||
required = {
|
||||
"ckpt_name": (
|
||||
folder_paths.get_filename_list("LLavacheckpoints"),
|
||||
),
|
||||
"clip_name": (
|
||||
folder_paths.get_filename_list("LLavacheckpoints"),
|
||||
),
|
||||
"max_ctx": (
|
||||
"INT",
|
||||
{"default": 4096, "min": 128, "max": 131072, "step": 64},
|
||||
),
|
||||
"gpu_layers": (
|
||||
"INT",
|
||||
{"default": 27, "min": -1, "max": 1000, "step": 1},
|
||||
),
|
||||
"n_threads": (
|
||||
"INT",
|
||||
{"default": 8, "min": 1, "max": 256, "step": 1},
|
||||
),
|
||||
"image": ("IMAGE",),
|
||||
"system_msg": (
|
||||
"STRING",
|
||||
{
|
||||
"default": (
|
||||
"You are an assistant who accurately describes images."
|
||||
)
|
||||
},
|
||||
),
|
||||
"prompt": ("STRING", {"default": "", "multiline": True}),
|
||||
"max_tokens": (
|
||||
"INT",
|
||||
{"default": 512, "min": 1, "max": 8192, "step": 1},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.1, "min": 0.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.95, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"top_k": ("INT", {"default": 40, "min": 0, "step": 1}),
|
||||
"frequency_penalty": (
|
||||
"FLOAT",
|
||||
{"default": 0.0, "min": -2.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"presence_penalty": (
|
||||
"FLOAT",
|
||||
{"default": 0.0, "min": -2.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"repeat_penalty": (
|
||||
"FLOAT",
|
||||
{"default": 1.1, "min": 0.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"seed": ("INT", {"default": 42, "step": 1}),
|
||||
"unload": ("BOOLEAN", {"default": False}),
|
||||
}
|
||||
return {"required": required}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "generate_text_advanced"
|
||||
CATEGORY = "VLM Nodes/LLava"
|
||||
|
||||
def generate_text_advanced(self, ckpt_name, clip_name, max_ctx, gpu_layers, n_threads, image, system_msg, prompt, max_tokens, temperature, top_p, top_k, frequency_penalty, presence_penalty, repeat_penalty, seed, unload):
|
||||
|
||||
# Load the clip
|
||||
clip_path = folder_paths.get_full_path("LLavacheckpoints", clip_name)
|
||||
self.clip = Llava15ChatHandler(clip_model_path=clip_path, verbose=False)
|
||||
|
||||
# Load model
|
||||
ckpt_path = folder_paths.get_full_path("LLavacheckpoints", ckpt_name)
|
||||
self.llm = Llama(model_path = ckpt_path, chat_handler=self.clip, offload_kqv=True, f16_kv=True, use_mlock=False, embedding=False, n_batch=1024, last_n_tokens_size=1024, verbose=True, seed=42, n_ctx = max_ctx, n_gpu_layers=gpu_layers, n_threads=n_threads, logits_all=True, echo=False)
|
||||
|
||||
# Assuming 'image' is a PyTorch tensor of shape [C, H, W]
|
||||
# Convert the PyTorch tensor to a PIL image
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
|
||||
# Convert the PIL image to a bytes buffer
|
||||
buffer = BytesIO()
|
||||
pil_image.save(buffer, format="PNG") # You can change the format if needed
|
||||
|
||||
# Get the bytes from the buffer
|
||||
image_bytes = buffer.getvalue()
|
||||
|
||||
# Encode the bytes to base64
|
||||
base64_string = f"data:image/jpeg;base64,{base64.b64encode(image_bytes).decode('utf-8')}"
|
||||
|
||||
# Now, `base64_string` contains the base64-encoded string of the image
|
||||
|
||||
response = self.llm.create_chat_completion(
|
||||
messages=[
|
||||
{"role": "system", "content": system_msg},
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "image_url", "image_url": {"url": base64_string}},
|
||||
{"type": "text", "text": f"{prompt}"}
|
||||
]
|
||||
}
|
||||
],
|
||||
max_tokens=max_tokens,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
top_k=top_k,
|
||||
frequency_penalty=frequency_penalty,
|
||||
presence_penalty=presence_penalty,
|
||||
repeat_penalty=repeat_penalty,
|
||||
seed=seed,
|
||||
def generate_text_advanced(
|
||||
self,
|
||||
ckpt_name,
|
||||
clip_name,
|
||||
max_ctx,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
image,
|
||||
system_msg,
|
||||
prompt,
|
||||
max_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
top_k,
|
||||
frequency_penalty,
|
||||
presence_penalty,
|
||||
repeat_penalty,
|
||||
seed,
|
||||
unload,
|
||||
):
|
||||
model = self._model(
|
||||
ckpt_name,
|
||||
clip_name,
|
||||
max_ctx,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
seed,
|
||||
)
|
||||
try:
|
||||
result = _run_batch(
|
||||
image,
|
||||
model,
|
||||
system_msg=system_msg,
|
||||
prompt=prompt,
|
||||
max_tokens=max_tokens,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
top_k=top_k,
|
||||
frequency_penalty=frequency_penalty,
|
||||
presence_penalty=presence_penalty,
|
||||
repeat_penalty=repeat_penalty,
|
||||
seed=seed,
|
||||
)
|
||||
return (result,)
|
||||
finally:
|
||||
self._maybe_unload(unload)
|
||||
|
||||
if unload and self.llm is not None:
|
||||
del self.llm # Unload the model
|
||||
self.llm = None # Remove reference to the model
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
if unload and self.clip is not None:
|
||||
del self.clip # Unload the clip
|
||||
self.clip = None # Remove reference to the clip
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
return (f"{response['choices'][0]['message']['content']}", )
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"LLava Loader Simple": LLavaLoader,
|
||||
@@ -370,12 +493,12 @@ NODE_CLASS_MAPPINGS = {
|
||||
"LLavaOptionalMemoryFreeSimple": LLavaOptionalMemoryFreeSimple,
|
||||
"LLavaOptionalMemoryFreeAdvanced": LLavaOptionalMemoryFreeAdvanced,
|
||||
}
|
||||
# A dictionary that contains the friendly/humanly readable titles for the nodes
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"LLava Loader Simple": "LLava Loader Simple",
|
||||
"LLavaSamplerSimple": "LLava Sampler Simple",
|
||||
"LlavaClipLoader": "Llava Clip Loader",
|
||||
"LLavaSamplerAdvanced": "LLava Sampler Advanced",
|
||||
"LLavaOptionalMemoryFreeSimple": "LLava Optional Memory Free Simple",
|
||||
"LLavaOptionalMemoryFreeAdvanced": "LLava Optional Memory Free Advanced",
|
||||
"LLava Loader Simple": "LLaVA Loader",
|
||||
"LLavaSamplerSimple": "LLaVA Sampler",
|
||||
"LlavaClipLoader": "LLaVA Vision Projector Loader",
|
||||
"LLavaSamplerAdvanced": "LLaVA Sampler (Advanced)",
|
||||
"LLavaOptionalMemoryFreeSimple": "LLaVA (Managed Cache)",
|
||||
"LLavaOptionalMemoryFreeAdvanced": "LLaVA (Managed Cache, Advanced)",
|
||||
}
|
||||
|
||||
+140
-66
@@ -1,88 +1,162 @@
|
||||
from transformers import AutoModelForCausalLM, AutoProcessor
|
||||
from PIL import Image
|
||||
from pathlib import Path
|
||||
"""MC-LLaVA node with in-memory images and ComfyUI-managed weights."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import torch
|
||||
from huggingface_hub import snapshot_download
|
||||
from torchvision.transforms import ToPILImage
|
||||
import io
|
||||
from PIL import Image
|
||||
import folder_paths
|
||||
# Define the directory for saving files related to the MCLLaVA model
|
||||
files_for_mcllava_model = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for_mcllava"
|
||||
files_for_mcllava_model.mkdir(parents=True, exist_ok=True) # Ensure the directory exists
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
inference_context,
|
||||
model_device,
|
||||
move_inputs,
|
||||
require_module,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
MODEL_ID = "visheratin/MC-LLaVA-3b"
|
||||
|
||||
|
||||
class MCLLaVAModelPredictor:
|
||||
def __init__(self):
|
||||
self.model_path = snapshot_download("visheratin/MC-LLaVA-3b",
|
||||
local_dir=files_for_mcllava_model,
|
||||
force_download=False, # Set to True if you always want to download, regardless of local copy
|
||||
local_files_only=False, # Set to False to allow downloading if not available locally
|
||||
local_dir_use_symlinks="auto", # or set to True/False based on your symlink preference
|
||||
ignore_patterns=["*.bin", "*.jpg", "*.png"]) # Exclude certain file types
|
||||
self.device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
self.model = AutoModelForCausalLM.from_pretrained(self.model_path, torch_dtype=torch.float16, trust_remote_code=True).to(self.device)
|
||||
self.processor = AutoProcessor.from_pretrained(self.model_path, trust_remote_code=True)
|
||||
transformers = require_module("transformers")
|
||||
model_path = snapshot_download(
|
||||
MODEL_ID, "mcllava", ignore_patterns=["*.bin"]
|
||||
)
|
||||
self.dtype = torch_dtype("float16")
|
||||
model = transformers.AutoModelForCausalLM.from_pretrained(
|
||||
model_path,
|
||||
torch_dtype=self.dtype,
|
||||
trust_remote_code=True,
|
||||
).eval()
|
||||
self.processor = transformers.AutoProcessor.from_pretrained(
|
||||
model_path, trust_remote_code=True
|
||||
)
|
||||
self.handle = ManagedTorchModel(model, processor=self.processor)
|
||||
|
||||
def generate_predictions(self, pil_image, prompt, temperature, top_p, max_crops, num_tokens):
|
||||
# Load the image
|
||||
# Save the PIL image to a bytes buffer instead of a file on disk.
|
||||
buffer = io.BytesIO()
|
||||
pil_image.save(buffer, format='PNG')
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
# Move to the beginning of the buffer so Image.open can read from it.
|
||||
buffer.seek(0)
|
||||
def generate(
|
||||
self,
|
||||
images,
|
||||
prompt,
|
||||
temperature,
|
||||
top_p,
|
||||
max_crops,
|
||||
num_tokens,
|
||||
max_new_tokens,
|
||||
):
|
||||
results = []
|
||||
formatted = (
|
||||
"<|im_start|>user\n<image>\n"
|
||||
f"{prompt}<|im_end|>\n<|im_start|>assistant\n"
|
||||
)
|
||||
for image in tensor_batch_to_pil(images):
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
inputs = self.processor(
|
||||
formatted,
|
||||
[image],
|
||||
model,
|
||||
max_crops=int(max_crops),
|
||||
num_tokens=int(num_tokens),
|
||||
)
|
||||
inputs = move_inputs(inputs, device)
|
||||
do_sample = float(temperature) > 0.0
|
||||
generation = {
|
||||
"max_new_tokens": int(max_new_tokens),
|
||||
"do_sample": do_sample,
|
||||
"use_cache": True,
|
||||
"eos_token_id": self.processor.tokenizer.eos_token_id,
|
||||
}
|
||||
if do_sample:
|
||||
generation.update(
|
||||
temperature=float(temperature), top_p=float(top_p)
|
||||
)
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
output = model.generate(**inputs, **generation)
|
||||
input_length = inputs["input_ids"].shape[-1]
|
||||
text = self.processor.tokenizer.decode(
|
||||
output[0, input_length:], skip_special_tokens=True
|
||||
)
|
||||
results.append(text.strip())
|
||||
return batch_text(results)
|
||||
|
||||
# Open the image as if it was a 'raw' image from an HTTP response.
|
||||
image_input = Image.open(buffer)
|
||||
|
||||
final_prompt = f"""<|im_start|>user
|
||||
<image>
|
||||
{prompt}<|im_end|>
|
||||
<|im_start|>assistant
|
||||
"""
|
||||
|
||||
with torch.inference_mode():
|
||||
inputs = self.processor(final_prompt, [image_input], self.model, max_crops=max_crops, num_tokens=num_tokens)
|
||||
|
||||
with torch.inference_mode():
|
||||
output = self.model.generate(**inputs, max_new_tokens=200, do_sample=False, use_cache=False, top_p=top_p, temperature=temperature, eos_token_id=self.processor.tokenizer.eos_token_id)
|
||||
|
||||
generated_text = self.processor.tokenizer.decode(output[0]).replace(final_prompt, "").replace("<|im_end|>", "")
|
||||
return generated_text
|
||||
|
||||
# Example of integrating MCLLaVAModelPredictor into a node-like structure
|
||||
class MCLLaVAModel:
|
||||
def __init__(self):
|
||||
self.predictor = MCLLaVAModelPredictor()
|
||||
|
||||
class MCLLaVAModel(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"prompt": ( "STRING",{"multiline": True, "default": "", },),
|
||||
"temperature": ( "FLOAT", {"default": 0.1, "min": 0.0, "max": 1.0, "step": 0.01},),
|
||||
"top_p": ( "FLOAT", {"default": 0.9, "min": 0.0, "max": 1.0, "step": 0.01},),
|
||||
"max_crops": ( "INT", {"default": 100, "min": 1, "max": 300, "step": 1},),
|
||||
"num_tokens": ( "INT", {"default": 728, "min": 1, "max": 2048, "step": 1},),
|
||||
"prompt": (
|
||||
"STRING",
|
||||
{"multiline": True, "default": "Describe the image."},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.1, "min": 0.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.9, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"max_crops": (
|
||||
"INT",
|
||||
{"default": 100, "min": 1, "max": 300, "step": 1},
|
||||
),
|
||||
"num_tokens": (
|
||||
"INT",
|
||||
{"default": 728, "min": 1, "max": 4096, "step": 1},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 200, "min": 1, "max": 4096},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
|
||||
FUNCTION = "generate_image_description"
|
||||
|
||||
CATEGORY = "VLM Nodes/MC-LLaVA"
|
||||
|
||||
def generate_image_description(self, image, prompt, temperature, top_p, max_crops, num_tokens):
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
|
||||
response = self.predictor.generate_predictions(pil_image, prompt, temperature, top_p, max_crops, num_tokens)
|
||||
return (response, )
|
||||
def generate_image_description(
|
||||
self,
|
||||
image,
|
||||
prompt,
|
||||
temperature,
|
||||
top_p,
|
||||
max_crops,
|
||||
num_tokens,
|
||||
max_new_tokens=200,
|
||||
unload_after=False,
|
||||
):
|
||||
predictor = self.get_or_create_model(
|
||||
MODEL_ID, MCLLaVAModelPredictor
|
||||
)
|
||||
try:
|
||||
return (
|
||||
predictor.generate(
|
||||
image,
|
||||
prompt,
|
||||
temperature,
|
||||
top_p,
|
||||
max_crops,
|
||||
num_tokens,
|
||||
max_new_tokens,
|
||||
),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"MCLLaVAModel": MCLLaVAModel}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"MCLLaVAModel": "MC-LLaVA Node"}
|
||||
|
||||
|
||||
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"MCLLaVAModel": "MC-LLaVA"}
|
||||
|
||||
+185
-160
@@ -1,188 +1,213 @@
|
||||
import os
|
||||
import subprocess
|
||||
import torch
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
from pathlib import Path
|
||||
from huggingface_hub import hf_hub_download
|
||||
import folder_paths
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
"""MiniCPM-V 2.6 GGUF node using llama.cpp's native vision handler."""
|
||||
|
||||
# Define the directory for saving MiniCPM files
|
||||
MINICPM_PATH = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "minicpm_files"
|
||||
MINICPM_PATH.mkdir(parents=True, exist_ok=True)
|
||||
from __future__ import annotations
|
||||
|
||||
# Available GGUF model variants and their file sizes (in GB)
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
LlamaHandle,
|
||||
batch_text,
|
||||
hf_download,
|
||||
image_data_uri,
|
||||
require_module,
|
||||
tensor_batch_to_pil,
|
||||
)
|
||||
|
||||
MODEL_REPO = "openbmb/MiniCPM-V-2_6-gguf"
|
||||
GGUF_MODELS = {
|
||||
"Q2_K (3GB)": "ggml-model-Q2_K.gguf",
|
||||
"Q3_K (3.8GB)": "ggml-model-Q3_K.gguf",
|
||||
"Q4_K_M (4.7GB)": "ggml-model-Q4_K_M.gguf",
|
||||
"Q5_K_M (5.4GB)": "ggml-model-Q5_K_M.gguf",
|
||||
"Q8_0 (8.1GB)": "ggml-model-Q8_0.gguf",
|
||||
"F16 (15.2GB)": "ggml-model-f16.gguf"
|
||||
"F16 (15.2GB)": "ggml-model-f16.gguf",
|
||||
}
|
||||
|
||||
|
||||
class MiniCPMPredictor:
|
||||
def __init__(self, model_name='openbmb/MiniCPM-V-2_6', context_length=4096, temp=0.7,
|
||||
top_p=0.8, top_k=100, repeat_penalty=1.05):
|
||||
self.context_length = context_length
|
||||
self.temp = temp
|
||||
self.top_p = top_p
|
||||
self.top_k = top_k
|
||||
self.repeat_penalty = repeat_penalty
|
||||
|
||||
# Load model and tokenizer
|
||||
print(f"Loading model: {model_name}...")
|
||||
self.model = AutoModel.from_pretrained(model_name, trust_remote_code=True,
|
||||
attn_implementation='sdpa', torch_dtype=torch.bfloat16).eval().cuda()
|
||||
self.tokenizer = AutoTokenizer.from_pretrained(model_name, trust_remote_code=True)
|
||||
print("Model loaded successfully.")
|
||||
|
||||
def generate(self, image_path, prompt):
|
||||
"""Generate response using the model"""
|
||||
image = Image.open(image_path).convert('RGB')
|
||||
msgs = [{'role': 'user', 'content': [image, prompt]}]
|
||||
|
||||
try:
|
||||
response = self.model.chat(
|
||||
image=None,
|
||||
msgs=msgs,
|
||||
tokenizer=self.tokenizer
|
||||
def __init__(
|
||||
self,
|
||||
model_variant,
|
||||
context_length,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
):
|
||||
model_path = hf_download(
|
||||
MODEL_REPO,
|
||||
GGUF_MODELS[model_variant],
|
||||
"minicpm-v-2_6-gguf",
|
||||
)
|
||||
projector_path = hf_download(
|
||||
MODEL_REPO,
|
||||
"mmproj-model-f16.gguf",
|
||||
"minicpm-v-2_6-gguf",
|
||||
)
|
||||
|
||||
def create_handler():
|
||||
chat = require_module(
|
||||
"llama_cpp.llama_chat_format", "llama-cpp-python"
|
||||
)
|
||||
handler_class = getattr(chat, "MiniCPMv26ChatHandler", None)
|
||||
if handler_class is None:
|
||||
raise RuntimeError(
|
||||
"Your llama-cpp-python build is too old for MiniCPM-V 2.6. "
|
||||
"Install a current CUDA or CPU wheel."
|
||||
)
|
||||
return handler_class(
|
||||
clip_model_path=str(projector_path), verbose=False
|
||||
)
|
||||
return response
|
||||
except Exception as e:
|
||||
return f"Error generating response: {str(e)}"
|
||||
|
||||
class MiniCPMNode:
|
||||
def __init__(self):
|
||||
self.predictor = None
|
||||
self.current_model = None
|
||||
self.handle = LlamaHandle(
|
||||
model_path,
|
||||
n_ctx=int(context_length),
|
||||
n_gpu_layers=int(gpu_layers),
|
||||
n_threads=int(n_threads),
|
||||
chat_handler_factory=create_handler,
|
||||
)
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
|
||||
def generate(
|
||||
self,
|
||||
images,
|
||||
prompt,
|
||||
temperature,
|
||||
top_p,
|
||||
top_k,
|
||||
repeat_penalty,
|
||||
max_tokens,
|
||||
):
|
||||
llm = self.handle.ensure_loaded()
|
||||
results = []
|
||||
for image in tensor_batch_to_pil(images):
|
||||
response = llm.create_chat_completion(
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "image_url",
|
||||
"image_url": {
|
||||
"url": image_data_uri(image)
|
||||
},
|
||||
},
|
||||
{"type": "text", "text": prompt},
|
||||
],
|
||||
}
|
||||
],
|
||||
max_tokens=int(max_tokens),
|
||||
temperature=float(temperature),
|
||||
top_p=float(top_p),
|
||||
top_k=int(top_k),
|
||||
repeat_penalty=float(repeat_penalty),
|
||||
)
|
||||
results.append(
|
||||
str(response["choices"][0]["message"]["content"]).strip()
|
||||
)
|
||||
return batch_text(results)
|
||||
|
||||
|
||||
class MiniCPMNode(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE", {"tooltip": "Input image to be analyzed by MiniCPM-V"}),
|
||||
"prompt": ("STRING", {
|
||||
"multiline": True,
|
||||
"default": "Describe this image in detail.",
|
||||
"tooltip": "Instructions for the model. Be specific about what aspects of the image you want analyzed."
|
||||
}),
|
||||
"model_variant": (list(GGUF_MODELS.keys()), {
|
||||
"tooltip": "Model size/quality tradeoff. Smaller models (Q2-Q4) are faster but less accurate. Larger models (Q8, F16) provide better quality but require more VRAM."
|
||||
}),
|
||||
"context_length": ("INT", {
|
||||
"default": 4096,
|
||||
"min": 512,
|
||||
"max": 8192,
|
||||
"tooltip": "Maximum length of text context. Larger values allow longer conversations but use more memory. Default 4096 works well for most cases."
|
||||
}),
|
||||
"temperature": ("FLOAT", {
|
||||
"default": 0.7,
|
||||
"min": 0.1,
|
||||
"max": 2.0,
|
||||
"step": 0.1,
|
||||
"tooltip": "Controls randomness in generation. Lower values (0.1-0.5) are more focused and deterministic. Higher values (0.8-2.0) increase creativity and variance."
|
||||
}),
|
||||
"top_p": ("FLOAT", {
|
||||
"default": 0.8,
|
||||
"min": 0.1,
|
||||
"max": 1.0,
|
||||
"step": 0.1,
|
||||
"tooltip": "Nucleus sampling threshold. Lower values make responses more focused. Higher values allow more diverse word choices."
|
||||
}),
|
||||
"top_k": ("INT", {
|
||||
"default": 100,
|
||||
"min": 1,
|
||||
"max": 1000,
|
||||
"tooltip": "Limits the number of tokens considered for each generation step. Lower values increase focus, higher values allow more variety."
|
||||
}),
|
||||
"repeat_penalty": ("FLOAT", {
|
||||
"default": 1.05,
|
||||
"min": 1.0,
|
||||
"max": 2.0,
|
||||
"step": 0.05,
|
||||
"tooltip": "Penalizes word repetition. Values above 1.0 discourage repeated phrases. Higher values (>1.3) may affect fluency."
|
||||
})
|
||||
}
|
||||
"image": ("IMAGE",),
|
||||
"prompt": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "Describe this image in detail.",
|
||||
},
|
||||
),
|
||||
"model_variant": (list(GGUF_MODELS),),
|
||||
"context_length": (
|
||||
"INT",
|
||||
{"default": 4096, "min": 512, "max": 131072},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.2, "min": 0.0, "max": 2.0, "step": 0.1},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.8, "min": 0.0, "max": 1.0, "step": 0.05},
|
||||
),
|
||||
"top_k": (
|
||||
"INT",
|
||||
{"default": 100, "min": 0, "max": 1000},
|
||||
),
|
||||
"repeat_penalty": (
|
||||
"FLOAT",
|
||||
{"default": 1.05, "min": 0.0, "max": 2.0, "step": 0.05},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"gpu_layers": (
|
||||
"INT",
|
||||
{"default": -1, "min": -1, "max": 1000},
|
||||
),
|
||||
"n_threads": (
|
||||
"INT",
|
||||
{"default": 8, "min": 1, "max": 256},
|
||||
),
|
||||
"max_tokens": (
|
||||
"INT",
|
||||
{"default": 512, "min": 1, "max": 8192},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "generate"
|
||||
CATEGORY = "VLM Nodes/MiniCPM-V"
|
||||
|
||||
def download_model(self, model_filename):
|
||||
"""Download model files from Huggingface"""
|
||||
def generate(
|
||||
self,
|
||||
image,
|
||||
prompt,
|
||||
model_variant,
|
||||
context_length=4096,
|
||||
temperature=0.2,
|
||||
top_p=0.8,
|
||||
top_k=100,
|
||||
repeat_penalty=1.05,
|
||||
gpu_layers=-1,
|
||||
n_threads=8,
|
||||
max_tokens=512,
|
||||
unload_after=False,
|
||||
):
|
||||
key = (
|
||||
model_variant,
|
||||
int(context_length),
|
||||
int(gpu_layers),
|
||||
int(n_threads),
|
||||
)
|
||||
predictor = self.get_or_create_model(
|
||||
key,
|
||||
lambda: MiniCPMPredictor(
|
||||
model_variant,
|
||||
context_length,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
),
|
||||
)
|
||||
try:
|
||||
print(f"Downloading model: {model_filename}...")
|
||||
model_path = hf_hub_download(
|
||||
repo_id="openbmb/MiniCPM-V-2_6-gguf",
|
||||
filename=model_filename,
|
||||
local_dir=MINICPM_PATH,
|
||||
local_dir_use_symlinks=False
|
||||
return (
|
||||
predictor.generate(
|
||||
image,
|
||||
prompt,
|
||||
temperature,
|
||||
top_p,
|
||||
top_k,
|
||||
repeat_penalty,
|
||||
max_tokens,
|
||||
),
|
||||
)
|
||||
|
||||
print("Downloading mmproj model if not exists...")
|
||||
mmproj_path = hf_hub_download(
|
||||
repo_id="openbmb/MiniCPM-V-2_6-gguf",
|
||||
filename="mmproj-model-f16.gguf",
|
||||
local_dir=MINICPM_PATH,
|
||||
local_dir_use_symlinks=False
|
||||
)
|
||||
|
||||
print("Download complete.")
|
||||
return Path(model_path), Path(mmproj_path)
|
||||
except Exception as e:
|
||||
raise RuntimeError(f"Error downloading model: {str(e)}")
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
def generate(self, image, prompt, model_variant, context_length=4096,
|
||||
temperature=0.7, top_p=0.8, top_k=100, repeat_penalty=1.05):
|
||||
|
||||
# Get model filename from variant name
|
||||
model_filename = GGUF_MODELS[model_variant]
|
||||
|
||||
# Initialize or update predictor if needed
|
||||
if (self.predictor is None or
|
||||
self.current_model != model_filename):
|
||||
|
||||
# Download model if needed
|
||||
model_path, mmproj_path = self.download_model(model_filename)
|
||||
|
||||
# Initialize predictor
|
||||
try:
|
||||
self.predictor = MiniCPMPredictor(
|
||||
model_name='openbmb/MiniCPM-V-2_6',
|
||||
context_length=context_length,
|
||||
temp=temperature,
|
||||
top_p=top_p,
|
||||
top_k=top_k,
|
||||
repeat_penalty=repeat_penalty
|
||||
)
|
||||
self.current_model = model_filename
|
||||
except Exception as e:
|
||||
return (f"Error initializing model: {str(e)}",)
|
||||
|
||||
# Save input image temporarily
|
||||
temp_image = MINICPM_PATH / "temp_input.png"
|
||||
Image.fromarray(np.uint8(image[0] * 255)).save(temp_image)
|
||||
|
||||
try:
|
||||
# Generate response
|
||||
response = self.predictor.generate(temp_image, prompt)
|
||||
|
||||
# Clean up
|
||||
temp_image.unlink(missing_ok=True)
|
||||
|
||||
return (response,)
|
||||
|
||||
except Exception as e:
|
||||
return (f"Error during generation: {str(e)}",)
|
||||
|
||||
# Register the node
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"MiniCPMNode": MiniCPMNode
|
||||
}
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"MiniCPMNode": "MiniCPM-V Model"
|
||||
}
|
||||
NODE_CLASS_MAPPINGS = {"MiniCPMNode": MiniCPMNode}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"MiniCPMNode": "MiniCPM-V 2.6 (GGUF)"}
|
||||
|
||||
@@ -0,0 +1,619 @@
|
||||
"""Modern, chat-template based vision-language models.
|
||||
|
||||
This node intentionally uses the Transformers multimodal auto classes instead
|
||||
of model-specific glue. It provides one stable ComfyUI surface for current
|
||||
small and large VLM families while keeping downloads and VRAM allocation lazy.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from dataclasses import dataclass
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ExternalTorchModel,
|
||||
ManagedTorchModel,
|
||||
accelerator_backend,
|
||||
batch_text,
|
||||
execution_device,
|
||||
external_device_map,
|
||||
inference_context,
|
||||
model_device,
|
||||
move_inputs,
|
||||
normalize_hf_model_id,
|
||||
require_quantization_backend,
|
||||
require_module,
|
||||
reserve_external_vram,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class ModelSpec:
|
||||
repo_id: str
|
||||
family: str
|
||||
estimated_gib: float
|
||||
gated: bool = False
|
||||
video: bool = False
|
||||
small_fast: bool = False
|
||||
trust_remote_code: bool = False
|
||||
|
||||
|
||||
# Deliberately curated: these are useful tiers, not every redundant checkpoint.
|
||||
MODEL_CATALOG = {
|
||||
"Qwen 3.5 0.8B (fastest current)": ModelSpec(
|
||||
"Qwen/Qwen3.5-0.8B",
|
||||
"Qwen 3.5",
|
||||
2.0,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Qwen 3.5 2B": ModelSpec(
|
||||
"Qwen/Qwen3.5-2B",
|
||||
"Qwen 3.5",
|
||||
4.5,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Qwen 3.5 4B (recommended)": ModelSpec(
|
||||
"Qwen/Qwen3.5-4B",
|
||||
"Qwen 3.5",
|
||||
8.5,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Qwen 3.5 9B": ModelSpec(
|
||||
"Qwen/Qwen3.5-9B", "Qwen 3.5", 19.0, video=True
|
||||
),
|
||||
"Qwen 3.5 27B (4-bit recommended)": ModelSpec(
|
||||
"Qwen/Qwen3.5-27B", "Qwen 3.5", 55.0, video=True
|
||||
),
|
||||
"Qwen 3.5 35B-A3B (4-bit recommended)": ModelSpec(
|
||||
"Qwen/Qwen3.5-35B-A3B", "Qwen 3.5", 72.0, video=True
|
||||
),
|
||||
"Qwen 3.6 27B (4-bit recommended)": ModelSpec(
|
||||
"Qwen/Qwen3.6-27B", "Qwen 3.6", 55.0, video=True
|
||||
),
|
||||
"Qwen 3 VL 2B Instruct": ModelSpec(
|
||||
"Qwen/Qwen3-VL-2B-Instruct",
|
||||
"Qwen 3 VL",
|
||||
5.0,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Qwen 3 VL 4B Instruct": ModelSpec(
|
||||
"Qwen/Qwen3-VL-4B-Instruct",
|
||||
"Qwen 3 VL",
|
||||
9.0,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Qwen 3 VL 8B Instruct": ModelSpec(
|
||||
"Qwen/Qwen3-VL-8B-Instruct", "Qwen 3 VL", 18.0, video=True
|
||||
),
|
||||
"Qwen 3 VL 30B-A3B Instruct (4-bit recommended)": ModelSpec(
|
||||
"Qwen/Qwen3-VL-30B-A3B-Instruct", "Qwen 3 VL", 61.0, video=True
|
||||
),
|
||||
"Qwen 2.5 VL 3B Instruct (legacy workflows)": ModelSpec(
|
||||
"Qwen/Qwen2.5-VL-3B-Instruct",
|
||||
"Qwen 2.5 VL",
|
||||
7.0,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Qwen 2.5 VL 7B Instruct (legacy workflows)": ModelSpec(
|
||||
"Qwen/Qwen2.5-VL-7B-Instruct", "Qwen 2.5 VL", 16.0, video=True
|
||||
),
|
||||
"Gemma 3 4B IT (license acceptance required)": ModelSpec(
|
||||
"google/gemma-3-4b-it",
|
||||
"Gemma 3",
|
||||
9.0,
|
||||
gated=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Gemma 3 12B IT (license acceptance required)": ModelSpec(
|
||||
"google/gemma-3-12b-it", "Gemma 3", 25.0, gated=True
|
||||
),
|
||||
"Gemma 3 27B IT (4-bit recommended, gated)": ModelSpec(
|
||||
"google/gemma-3-27b-it", "Gemma 3", 55.0, gated=True
|
||||
),
|
||||
"SmolVLM2 256M Video (smallest)": ModelSpec(
|
||||
"HuggingFaceTB/SmolVLM2-256M-Video-Instruct",
|
||||
"SmolVLM2",
|
||||
1.4,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"SmolVLM2 500M Video (low VRAM)": ModelSpec(
|
||||
"HuggingFaceTB/SmolVLM2-500M-Video-Instruct",
|
||||
"SmolVLM2",
|
||||
1.8,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"SmolVLM2 2.2B Video": ModelSpec(
|
||||
"HuggingFaceTB/SmolVLM2-2.2B-Instruct",
|
||||
"SmolVLM2",
|
||||
5.2,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"LFM2.5 VL 450M (edge)": ModelSpec(
|
||||
"LiquidAI/LFM2.5-VL-450M",
|
||||
"LFM2.5 VL",
|
||||
1.5,
|
||||
small_fast=True,
|
||||
),
|
||||
"LFM2.5 VL 1.6B": ModelSpec(
|
||||
"LiquidAI/LFM2.5-VL-1.6B",
|
||||
"LFM2.5 VL",
|
||||
4.0,
|
||||
small_fast=True,
|
||||
),
|
||||
"InternVL 3.5 1B HF": ModelSpec(
|
||||
"OpenGVLab/InternVL3_5-1B-HF",
|
||||
"InternVL 3.5",
|
||||
2.5,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"InternVL 3.5 2B HF": ModelSpec(
|
||||
"OpenGVLab/InternVL3_5-2B-HF",
|
||||
"InternVL 3.5",
|
||||
5.0,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Granite Vision 3.3 2B (documents/OCR)": ModelSpec(
|
||||
"ibm-granite/granite-vision-3.3-2b",
|
||||
"Granite Vision 3.3",
|
||||
6.5,
|
||||
small_fast=True,
|
||||
),
|
||||
"Granite Vision 4.1 4B (structured documents)": ModelSpec(
|
||||
"ibm-granite/granite-vision-4.1-4b",
|
||||
"Granite Vision 4.1",
|
||||
9.0,
|
||||
small_fast=True,
|
||||
),
|
||||
"Custom Hugging Face model": ModelSpec(
|
||||
"",
|
||||
"Custom",
|
||||
8.0,
|
||||
trust_remote_code=True,
|
||||
),
|
||||
}
|
||||
|
||||
MEMORY_MODES = (
|
||||
"ComfyUI managed (BF16)",
|
||||
"4-bit NF4 (bitsandbytes)",
|
||||
"8-bit (bitsandbytes)",
|
||||
"CPU",
|
||||
)
|
||||
ATTENTION_MODES = ("Auto (SDPA)", "Flash Attention 2", "Eager")
|
||||
|
||||
|
||||
def _model_class(transformers):
|
||||
for name in ("AutoModelForImageTextToText", "AutoModelForMultimodalLM"):
|
||||
model_class = getattr(transformers, name, None)
|
||||
if model_class is not None:
|
||||
return model_class
|
||||
raise RuntimeError(
|
||||
"Modern VLMs require a current Transformers release with "
|
||||
"AutoModelForImageTextToText support."
|
||||
)
|
||||
|
||||
|
||||
class ModernVLMPredictor:
|
||||
def __init__(
|
||||
self,
|
||||
model_label: str,
|
||||
custom_model_id: str,
|
||||
memory_mode: str,
|
||||
attention_mode: str,
|
||||
) -> None:
|
||||
transformers = require_module("transformers")
|
||||
spec = MODEL_CATALOG[model_label]
|
||||
repo_id = (
|
||||
normalize_hf_model_id(custom_model_id)
|
||||
if spec.family == "Custom"
|
||||
else spec.repo_id
|
||||
)
|
||||
self.spec = spec
|
||||
self.dtype = torch_dtype("bfloat16")
|
||||
if (
|
||||
attention_mode == "Flash Attention 2"
|
||||
and accelerator_backend(execution_device())
|
||||
not in {"nvidia-cuda", "amd-rocm"}
|
||||
):
|
||||
raise RuntimeError(
|
||||
"Flash Attention 2 requires a supported CUDA or ROCm build. "
|
||||
"Select Auto (SDPA) on Apple Metal, Intel XPU, or CPU."
|
||||
)
|
||||
quantization_device = None
|
||||
if memory_mode in {
|
||||
"4-bit NF4 (bitsandbytes)",
|
||||
"8-bit (bitsandbytes)",
|
||||
}:
|
||||
# Validate before downloading a multi-gigabyte checkpoint.
|
||||
quantization_device = require_quantization_backend(memory_mode)
|
||||
try:
|
||||
model_path = snapshot_download(
|
||||
repo_id,
|
||||
f"modern-vlm/{repo_id.replace('/', '--')}",
|
||||
ignore_patterns=["*.bin", "*.msgpack", "*.h5", "*.onnx"],
|
||||
)
|
||||
except Exception as exc:
|
||||
if spec.gated:
|
||||
raise RuntimeError(
|
||||
f"{repo_id} is gated. Accept its Hugging Face license and "
|
||||
"set HF_TOKEN before running this node."
|
||||
) from exc
|
||||
raise
|
||||
self.processor = transformers.AutoProcessor.from_pretrained(
|
||||
model_path,
|
||||
trust_remote_code=spec.trust_remote_code,
|
||||
)
|
||||
|
||||
attention = {
|
||||
# Let each architecture choose its maintained native kernel. Most
|
||||
# current PyTorch models select SDPA here, while hybrid edge models
|
||||
# can retain their own attention implementation.
|
||||
"Auto (SDPA)": None,
|
||||
"Flash Attention 2": "flash_attention_2",
|
||||
"Eager": "eager",
|
||||
}[attention_mode]
|
||||
kwargs: dict[str, Any] = {
|
||||
"dtype": self.dtype,
|
||||
"trust_remote_code": spec.trust_remote_code,
|
||||
}
|
||||
if attention is not None:
|
||||
kwargs["attn_implementation"] = attention
|
||||
external = memory_mode != "ComfyUI managed (BF16)"
|
||||
if memory_mode in {"4-bit NF4 (bitsandbytes)", "8-bit (bitsandbytes)"}:
|
||||
assert quantization_device is not None
|
||||
needs_offload = spec.estimated_gib >= 40.0
|
||||
kwargs["quantization_config"] = transformers.BitsAndBytesConfig(
|
||||
load_in_4bit=memory_mode.startswith("4-bit"),
|
||||
load_in_8bit=memory_mode.startswith("8-bit"),
|
||||
bnb_4bit_compute_dtype=self.dtype,
|
||||
bnb_4bit_quant_type="nf4",
|
||||
bnb_4bit_use_double_quant=True,
|
||||
llm_int8_enable_fp32_cpu_offload=needs_offload,
|
||||
)
|
||||
if needs_offload:
|
||||
# Automatic CPU/disk placement is maintained for CUDA, ROCm,
|
||||
# and XPU. MPS uses unified memory and CPU already runs in RAM,
|
||||
# so both stay on their explicit active device.
|
||||
kwargs["device_map"] = external_device_map(
|
||||
allow_auto_offload=True
|
||||
)
|
||||
kwargs["offload_folder"] = str(model_path / ".offload")
|
||||
else:
|
||||
# Avoid accidental dispatch to device zero when ComfyUI chose
|
||||
# another GPU, Apple Metal, Intel XPU, or CPU.
|
||||
kwargs["device_map"] = external_device_map()
|
||||
divisor = 4 if memory_mode.startswith("4-bit") else 2
|
||||
if quantization_device.type != "cpu":
|
||||
reserve_external_vram(
|
||||
int(spec.estimated_gib * 1024**3 / divisor)
|
||||
)
|
||||
elif memory_mode == "CPU":
|
||||
kwargs["dtype"] = torch.float32
|
||||
|
||||
try:
|
||||
model = _model_class(transformers).from_pretrained(
|
||||
model_path, **kwargs
|
||||
).eval()
|
||||
except OSError as exc:
|
||||
if spec.gated:
|
||||
raise RuntimeError(
|
||||
f"{repo_id} is gated. Accept its Hugging Face license and "
|
||||
"set HF_TOKEN before running this node."
|
||||
) from exc
|
||||
raise
|
||||
except ImportError as exc:
|
||||
if attention_mode == "Flash Attention 2":
|
||||
raise RuntimeError(
|
||||
"Flash Attention 2 is unavailable for this Python/PyTorch "
|
||||
"build. Select Auto (SDPA), or install a matching wheel."
|
||||
) from exc
|
||||
raise
|
||||
|
||||
self.handle = (
|
||||
ExternalTorchModel(model, processor=self.processor)
|
||||
if external
|
||||
else ManagedTorchModel(model, processor=self.processor)
|
||||
)
|
||||
|
||||
def close(self) -> None:
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
def _inputs(
|
||||
self,
|
||||
messages,
|
||||
enable_thinking: bool = False,
|
||||
*,
|
||||
video_metadata: dict[str, Any] | None = None,
|
||||
):
|
||||
"""Use the standard multimodal template, with an older-template fallback."""
|
||||
|
||||
template_kwargs = (
|
||||
{"enable_thinking": bool(enable_thinking)}
|
||||
if self.spec.family in {"Qwen 3.5", "Qwen 3.6"}
|
||||
else {}
|
||||
)
|
||||
processor_kwargs = (
|
||||
{
|
||||
"video_metadata": [[video_metadata]],
|
||||
# ComfyUI already supplied the selected frames as a batch.
|
||||
"do_sample_frames": False,
|
||||
}
|
||||
if video_metadata is not None
|
||||
else None
|
||||
)
|
||||
if processor_kwargs is not None and self.spec.family == "InternVL 3.5":
|
||||
# The published InternVL 3.5 video preprocessor uses 384px, which
|
||||
# makes a 27x27 patch grid with its 14px vision patches. The
|
||||
# model's 0.5 pixel shuffle requires even spatial dimensions.
|
||||
image_size = getattr(self.processor.image_processor, "size", None)
|
||||
processor_kwargs["size"] = (
|
||||
dict(image_size)
|
||||
if image_size is not None
|
||||
else {"height": 448, "width": 448}
|
||||
)
|
||||
try:
|
||||
return self.processor.apply_chat_template(
|
||||
messages,
|
||||
add_generation_prompt=True,
|
||||
tokenize=True,
|
||||
return_dict=True,
|
||||
return_tensors="pt",
|
||||
processor_kwargs=processor_kwargs,
|
||||
**template_kwargs,
|
||||
)
|
||||
except (TypeError, ValueError, KeyError):
|
||||
media = []
|
||||
portable_messages = []
|
||||
for message in messages:
|
||||
content = []
|
||||
for part in message["content"]:
|
||||
if part["type"] == "image":
|
||||
media.append(part["image"])
|
||||
content.append({"type": "image"})
|
||||
elif part["type"] == "video":
|
||||
media.extend(part["video"])
|
||||
content.extend({"type": "image"} for _ in part["video"])
|
||||
else:
|
||||
content.append(part)
|
||||
portable_messages.append(
|
||||
{"role": message["role"], "content": content}
|
||||
)
|
||||
prompt = self.processor.apply_chat_template(
|
||||
portable_messages,
|
||||
add_generation_prompt=True,
|
||||
tokenize=False,
|
||||
**template_kwargs,
|
||||
)
|
||||
return self.processor(
|
||||
text=[prompt], images=media, return_tensors="pt"
|
||||
)
|
||||
|
||||
def generate(
|
||||
self,
|
||||
images,
|
||||
prompt: str,
|
||||
system_prompt: str,
|
||||
max_new_tokens: int,
|
||||
temperature: float,
|
||||
top_p: float,
|
||||
video_frames=None,
|
||||
fps: float = 1.0,
|
||||
enable_thinking: bool = False,
|
||||
) -> str:
|
||||
primary_images = (
|
||||
tensor_batch_to_pil(images) if images is not None else []
|
||||
)
|
||||
video = (
|
||||
tensor_batch_to_pil(video_frames)
|
||||
if video_frames is not None
|
||||
else None
|
||||
)
|
||||
if video is None and not primary_images:
|
||||
raise ValueError("Connect either image or video_frames.")
|
||||
if video is not None and not self.spec.video:
|
||||
raise ValueError(
|
||||
f"{self.spec.family} does not advertise video support. "
|
||||
"Disconnect video_frames or select Qwen/SmolVLM2."
|
||||
)
|
||||
|
||||
results = []
|
||||
# A connected video is the primary visual input. Including ComfyUI's
|
||||
# required still image as well makes small video models attend to the
|
||||
# still and silently ignore the frames.
|
||||
runs = [None] if video is not None else primary_images
|
||||
for image in runs:
|
||||
messages = []
|
||||
if system_prompt.strip():
|
||||
messages.append(
|
||||
{
|
||||
"role": "system",
|
||||
"content": [
|
||||
{"type": "text", "text": system_prompt.strip()}
|
||||
],
|
||||
}
|
||||
)
|
||||
content = (
|
||||
[{"type": "video", "video": video}]
|
||||
if video is not None
|
||||
else [{"type": "image", "image": image}]
|
||||
)
|
||||
effective_prompt = (
|
||||
f"The video frames are sampled at {float(fps):g} FPS.\n\n{prompt}"
|
||||
if video is not None
|
||||
else prompt
|
||||
)
|
||||
content.append({"type": "text", "text": effective_prompt})
|
||||
messages.append({"role": "user", "content": content})
|
||||
|
||||
metadata = None
|
||||
if video is not None:
|
||||
frame_rate = float(fps)
|
||||
metadata = {
|
||||
"total_num_frames": len(video),
|
||||
"fps": frame_rate,
|
||||
"duration": len(video) / frame_rate,
|
||||
"frames_indices": list(range(len(video))),
|
||||
"width": video[0].width,
|
||||
"height": video[0].height,
|
||||
}
|
||||
inputs = self._inputs(
|
||||
messages,
|
||||
enable_thinking,
|
||||
video_metadata=metadata,
|
||||
)
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
inputs = move_inputs(inputs, device)
|
||||
input_length = inputs["input_ids"].shape[-1]
|
||||
generation: dict[str, Any] = {
|
||||
"max_new_tokens": int(max_new_tokens),
|
||||
"do_sample": float(temperature) > 0,
|
||||
}
|
||||
if generation["do_sample"]:
|
||||
generation.update(
|
||||
temperature=float(temperature), top_p=float(top_p)
|
||||
)
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
output = model.generate(**inputs, **generation)
|
||||
new_tokens = output[:, input_length:]
|
||||
results.append(
|
||||
self.processor.batch_decode(
|
||||
new_tokens,
|
||||
skip_special_tokens=True,
|
||||
clean_up_tokenization_spaces=False,
|
||||
)[0].strip()
|
||||
)
|
||||
return batch_text(results)
|
||||
|
||||
|
||||
class ModernVLM(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"prompt": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "Describe this image precisely and in detail.",
|
||||
},
|
||||
),
|
||||
"model": (
|
||||
list(MODEL_CATALOG),
|
||||
{"default": "Qwen 3 VL 2B Instruct"},
|
||||
),
|
||||
"custom_model_id": ("STRING", {"default": ""}),
|
||||
"memory_mode": (
|
||||
MEMORY_MODES,
|
||||
{"default": "ComfyUI managed (BF16)"},
|
||||
),
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 512, "min": 1, "max": 16384},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.1, "min": 0.0, "max": 2.0, "step": 0.05},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.9, "min": 0.01, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"image": ("IMAGE",),
|
||||
"system_prompt": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "You are an expert visual analyst.",
|
||||
},
|
||||
),
|
||||
"video_frames": ("IMAGE",),
|
||||
"fps": (
|
||||
"FLOAT",
|
||||
{"default": 1.0, "min": 0.1, "max": 60.0, "step": 0.1},
|
||||
),
|
||||
"attention_mode": (
|
||||
ATTENTION_MODES,
|
||||
{"default": "Auto (SDPA)"},
|
||||
),
|
||||
"enable_thinking": ("BOOLEAN", {"default": False}),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "run"
|
||||
CATEGORY = "VLM Nodes/Modern"
|
||||
|
||||
def run(
|
||||
self,
|
||||
prompt,
|
||||
model,
|
||||
custom_model_id,
|
||||
memory_mode,
|
||||
max_new_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
image=None,
|
||||
system_prompt="You are an expert visual analyst.",
|
||||
video_frames=None,
|
||||
fps=1.0,
|
||||
attention_mode="Auto (SDPA)",
|
||||
enable_thinking=False,
|
||||
unload_after=False,
|
||||
):
|
||||
effective_custom_id = (
|
||||
normalize_hf_model_id(custom_model_id)
|
||||
if model == "Custom Hugging Face model"
|
||||
else ""
|
||||
)
|
||||
key = (model, effective_custom_id, memory_mode, attention_mode)
|
||||
predictor = self.get_or_create_model(
|
||||
key,
|
||||
lambda: ModernVLMPredictor(
|
||||
model, effective_custom_id, memory_mode, attention_mode
|
||||
),
|
||||
)
|
||||
try:
|
||||
return (
|
||||
predictor.generate(
|
||||
image,
|
||||
prompt,
|
||||
system_prompt,
|
||||
max_new_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
video_frames,
|
||||
fps,
|
||||
enable_thinking,
|
||||
),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"ModernVLM": ModernVLM}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"ModernVLM": (
|
||||
"Modern VLM (Qwen / SmolVLM2 / LFM / InternVL / Granite / Gemma)"
|
||||
)
|
||||
}
|
||||
+166
-315
@@ -1,345 +1,196 @@
|
||||
"""AllenAI Molmo nodes with batch support and deterministic model ownership."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
import os
|
||||
from PIL import Image
|
||||
from pathlib import Path
|
||||
import folder_paths
|
||||
import logging
|
||||
import warnings
|
||||
from transformers import AutoModelForCausalLM, AutoProcessor, GenerationConfig, BitsAndBytesConfig
|
||||
from huggingface_hub import snapshot_download
|
||||
import torch.amp.autocast_mode
|
||||
import psutil
|
||||
|
||||
# Configure logging
|
||||
logging.basicConfig(level=logging.INFO)
|
||||
logger = logging.getLogger('MolmoNode')
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ExternalTorchModel,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
external_device_map,
|
||||
inference_context,
|
||||
model_device,
|
||||
require_quantization_backend,
|
||||
require_module,
|
||||
reserve_external_vram,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
# Filter specific warnings
|
||||
warnings.filterwarnings('ignore', message='.*The model weights are not tied.*')
|
||||
warnings.filterwarnings('ignore', message='.*You should use.*max_memory.*')
|
||||
|
||||
# Define the directory for saving Molmo files
|
||||
MOLMO_PATH = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for_molmo"
|
||||
MOLMO_PATH.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
# Memory configurations with detailed descriptions
|
||||
MEMORY_MODES = {
|
||||
"Full Precision (45GB+ Required)": {
|
||||
"description": "Uses full FP16 precision. Requires ~45GB total system RAM, including 24GB+ VRAM.",
|
||||
"load_in_8bit": False,
|
||||
"load_in_4bit": False,
|
||||
"double_quant": False,
|
||||
"cpu_offload": False
|
||||
},
|
||||
"8-bit Quantized (25GB+ Required)": {
|
||||
"description": "Uses 8-bit quantization. Requires ~25GB total system RAM. Good balance of quality and memory usage.",
|
||||
"load_in_8bit": True,
|
||||
"load_in_4bit": False,
|
||||
"double_quant": False,
|
||||
"cpu_offload": False
|
||||
},
|
||||
"4-bit Quantized (15GB+ Required)": {
|
||||
"description": "Uses 4-bit quantization. Requires ~15GB total system RAM. Lowest memory usage, slight quality impact.",
|
||||
"load_in_8bit": False,
|
||||
"load_in_4bit": True,
|
||||
"double_quant": True,
|
||||
"cpu_offload": False
|
||||
},
|
||||
"4-bit + CPU Offload (12GB+ Required)": {
|
||||
"description": "Uses 4-bit quantization with CPU offloading. Slowest but lowest VRAM usage (~12GB).",
|
||||
"load_in_8bit": False,
|
||||
"load_in_4bit": True,
|
||||
"double_quant": True,
|
||||
"cpu_offload": True
|
||||
}
|
||||
"Full Precision (45GB+ Required)": "managed",
|
||||
"8-bit Quantized (25GB+ Required)": "8bit",
|
||||
"4-bit Quantized (15GB+ Required)": "4bit",
|
||||
"4-bit + CPU Offload (12GB+ Required)": "4bit-offload",
|
||||
}
|
||||
|
||||
# Available Molmo models
|
||||
MOLMO_MODELS = {
|
||||
"MolmoE-1B (Efficient)": {
|
||||
"repo": "allenai/MolmoE-1B-0924",
|
||||
"description": "Mixture-of-Experts model, smallest option (still requires significant RAM)"
|
||||
},
|
||||
"Molmo-7B-D (Best 7B)": {
|
||||
"repo": "allenai/Molmo-7B-D-0924",
|
||||
"description": "⚠️ Very large model, requires more RAM than MolmoE-1B"
|
||||
},
|
||||
"Molmo-7B-O (Alternative 7B)": {
|
||||
"repo": "allenai/Molmo-7B-O-0924",
|
||||
"description": "⚠️ Very large model, requires more RAM than MolmoE-1B"
|
||||
}
|
||||
"MolmoE-1B (Efficient)": "allenai/MolmoE-1B-0924",
|
||||
"Molmo-7B-D (Best 7B)": "allenai/Molmo-7B-D-0924",
|
||||
"Molmo-7B-O (Alternative 7B)": "allenai/Molmo-7B-O-0924",
|
||||
}
|
||||
|
||||
class SystemResources:
|
||||
@staticmethod
|
||||
def get_system_memory():
|
||||
return psutil.virtual_memory().total / (1024 ** 3) # GB
|
||||
|
||||
@staticmethod
|
||||
def get_available_vram():
|
||||
if not torch.cuda.is_available():
|
||||
return 0
|
||||
return torch.cuda.get_device_properties(0).total_memory / (1024 ** 3) # GB
|
||||
|
||||
@staticmethod
|
||||
def check_memory_requirements(memory_mode):
|
||||
config = MEMORY_MODES[memory_mode]
|
||||
required_ram = 15 if config["load_in_4bit"] else (25 if config["load_in_8bit"] else 45)
|
||||
available_ram = SystemResources.get_system_memory()
|
||||
available_vram = SystemResources.get_available_vram()
|
||||
|
||||
warnings = []
|
||||
if available_ram < required_ram:
|
||||
warnings.append(f"WARNING: This memory mode requires {required_ram}GB total RAM, but only {available_ram:.1f}GB available")
|
||||
|
||||
min_vram = 12 if config["cpu_offload"] else 24
|
||||
if available_vram < min_vram:
|
||||
warnings.append(f"WARNING: Recommended minimum {min_vram}GB VRAM, but only {available_vram:.1f}GB available")
|
||||
|
||||
return warnings
|
||||
|
||||
class MolmoPredictor:
|
||||
def __init__(self, model_name, memory_mode="4-bit Quantized (15GB+ Required)", use_autocast=True):
|
||||
self.model_name = MOLMO_MODELS[model_name]["repo"]
|
||||
self.memory_config = MEMORY_MODES[memory_mode]
|
||||
self.use_autocast = use_autocast and torch.cuda.is_available()
|
||||
|
||||
# Check system resources
|
||||
warnings = SystemResources.check_memory_requirements(memory_mode)
|
||||
for warning in warnings:
|
||||
logger.warning(warning)
|
||||
|
||||
# Download model if needed
|
||||
logger.info(f"Downloading/loading {model_name} in {memory_mode} mode...")
|
||||
self.model_path = snapshot_download(
|
||||
self.model_name,
|
||||
local_dir=MOLMO_PATH / model_name,
|
||||
local_dir_use_symlinks="auto"
|
||||
def __init__(self, model_name, memory_mode, use_autocast):
|
||||
transformers = require_module("transformers")
|
||||
repo_id = MOLMO_MODELS[model_name]
|
||||
mode = MEMORY_MODES[memory_mode]
|
||||
external = mode != "managed"
|
||||
if external:
|
||||
# Validate before downloading a multi-gigabyte checkpoint.
|
||||
require_quantization_backend(memory_mode)
|
||||
path = snapshot_download(
|
||||
repo_id,
|
||||
f"molmo/{repo_id.replace('/', '--')}",
|
||||
ignore_patterns=["*.bin"],
|
||||
)
|
||||
|
||||
try:
|
||||
# Configure quantization
|
||||
compute_dtype = torch.float16 if torch.cuda.is_available() else torch.float32
|
||||
quant_config = None
|
||||
|
||||
if self.memory_config["load_in_4bit"] or self.memory_config["load_in_8bit"]:
|
||||
quant_config = BitsAndBytesConfig(
|
||||
load_in_8bit=self.memory_config["load_in_8bit"],
|
||||
load_in_4bit=self.memory_config["load_in_4bit"],
|
||||
bnb_4bit_compute_dtype=compute_dtype,
|
||||
bnb_4bit_use_double_quant=self.memory_config["double_quant"],
|
||||
bnb_4bit_quant_type="nf4" # More accurate than fp4
|
||||
)
|
||||
|
||||
# Load processor
|
||||
self.processor = AutoProcessor.from_pretrained(
|
||||
self.model_path,
|
||||
trust_remote_code=True
|
||||
self.dtype = torch_dtype("bfloat16")
|
||||
self.use_autocast = bool(use_autocast)
|
||||
self.processor = transformers.AutoProcessor.from_pretrained(
|
||||
path, trust_remote_code=True
|
||||
)
|
||||
kwargs: dict[str, Any] = {
|
||||
"trust_remote_code": True,
|
||||
"dtype": self.dtype,
|
||||
}
|
||||
if external:
|
||||
kwargs["quantization_config"] = transformers.BitsAndBytesConfig(
|
||||
load_in_8bit=mode == "8bit",
|
||||
load_in_4bit=mode.startswith("4bit"),
|
||||
bnb_4bit_compute_dtype=self.dtype,
|
||||
bnb_4bit_quant_type="nf4",
|
||||
bnb_4bit_use_double_quant=True,
|
||||
)
|
||||
|
||||
# Load model with optimizations
|
||||
device_map = "auto" if self.memory_config["cpu_offload"] else None
|
||||
self.model = AutoModelForCausalLM.from_pretrained(
|
||||
self.model_path,
|
||||
trust_remote_code=True,
|
||||
quantization_config=quant_config,
|
||||
device_map=device_map,
|
||||
torch_dtype=compute_dtype
|
||||
kwargs["device_map"] = external_device_map(
|
||||
allow_auto_offload=mode == "4bit-offload"
|
||||
)
|
||||
|
||||
logger.info(f"Successfully loaded {model_name}")
|
||||
|
||||
except RuntimeError as e:
|
||||
if "out of memory" in str(e):
|
||||
torch.cuda.empty_cache()
|
||||
raise RuntimeError(
|
||||
f"Out of memory while loading model. Current mode: {memory_mode}\n"
|
||||
"Try:\n"
|
||||
"1. Using a more aggressive memory saving mode\n"
|
||||
"2. Closing other applications\n"
|
||||
"3. Restarting ComfyUI"
|
||||
) from e
|
||||
raise
|
||||
reserve_external_vram(
|
||||
(5 if "1B" in model_name else 12) * 1024**3
|
||||
)
|
||||
model = transformers.AutoModelForCausalLM.from_pretrained(
|
||||
path, **kwargs
|
||||
).eval()
|
||||
self.handle = (
|
||||
ExternalTorchModel(model, processor=self.processor)
|
||||
if external
|
||||
else ManagedTorchModel(model, processor=self.processor)
|
||||
)
|
||||
|
||||
def generate(self, image, prompt, max_new_tokens=200, temperature=0.7, top_p=0.9, top_k=50):
|
||||
try:
|
||||
# Process inputs
|
||||
inputs = self.processor.process(
|
||||
images=[image],
|
||||
text=prompt
|
||||
)
|
||||
|
||||
# Move inputs to device and create batch
|
||||
device = next(self.model.parameters()).device
|
||||
inputs = {k: v.to(device).unsqueeze(0) for k, v in inputs.items()}
|
||||
|
||||
# Configure generation
|
||||
generation_config = GenerationConfig(
|
||||
max_new_tokens=max_new_tokens,
|
||||
do_sample=True,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
top_k=top_k,
|
||||
stop_strings="<|endoftext|>",
|
||||
pad_token_id=self.processor.tokenizer.pad_token_id,
|
||||
eos_token_id=self.processor.tokenizer.eos_token_id
|
||||
)
|
||||
|
||||
# Generate with autocast if enabled
|
||||
if self.use_autocast:
|
||||
with torch.amp.autocast(device_type="cuda", dtype=torch.bfloat16):
|
||||
output = self.model.generate_from_batch(
|
||||
inputs,
|
||||
generation_config,
|
||||
tokenizer=self.processor.tokenizer
|
||||
)
|
||||
else:
|
||||
output = self.model.generate_from_batch(
|
||||
inputs,
|
||||
generation_config,
|
||||
tokenizer=self.processor.tokenizer
|
||||
)
|
||||
|
||||
# Get input size before cleanup
|
||||
input_size = inputs['input_ids'].size(1)
|
||||
|
||||
# Clean up
|
||||
del inputs
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
# Extract and decode generated tokens using saved size
|
||||
generated_tokens = output[0, input_size:]
|
||||
return self.processor.tokenizer.decode(generated_tokens, skip_special_tokens=True)
|
||||
|
||||
except RuntimeError as e:
|
||||
if "out of memory" in str(e):
|
||||
torch.cuda.empty_cache()
|
||||
raise RuntimeError(
|
||||
"Out of memory during generation. Try:\n"
|
||||
"1. Using a more aggressive memory saving mode\n"
|
||||
"2. Reducing max_new_tokens\n"
|
||||
"3. Clearing ComfyUI cache\n"
|
||||
"4. Restarting ComfyUI"
|
||||
) from e
|
||||
raise
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
class MolmoNode:
|
||||
def __init__(self):
|
||||
self.predictor = None
|
||||
self.current_model = None
|
||||
self.current_memory_mode = None
|
||||
self.current_autocast = None
|
||||
def generate(self, image, prompt, max_new_tokens, temperature, top_p, top_k):
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
inputs = self.processor.process(images=[image], text=prompt)
|
||||
inputs = {
|
||||
key: value.to(device).unsqueeze(0)
|
||||
for key, value in inputs.items()
|
||||
}
|
||||
config = require_module("transformers").GenerationConfig(
|
||||
max_new_tokens=int(max_new_tokens),
|
||||
do_sample=float(temperature) > 0,
|
||||
temperature=max(float(temperature), 1e-5),
|
||||
top_p=float(top_p),
|
||||
top_k=int(top_k),
|
||||
stop_strings="<|endoftext|>",
|
||||
pad_token_id=self.processor.tokenizer.pad_token_id,
|
||||
eos_token_id=self.processor.tokenizer.eos_token_id,
|
||||
)
|
||||
context = (
|
||||
inference_context(device, self.dtype)
|
||||
if self.use_autocast
|
||||
else torch.no_grad()
|
||||
)
|
||||
with torch.inference_mode(), context:
|
||||
output = model.generate_from_batch(
|
||||
inputs, config, tokenizer=self.processor.tokenizer
|
||||
)
|
||||
return self.processor.tokenizer.decode(
|
||||
output[0, inputs["input_ids"].shape[1]:],
|
||||
skip_special_tokens=True,
|
||||
).strip()
|
||||
|
||||
|
||||
class MolmoNode(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE", {
|
||||
"tooltip": "Input image to be analyzed by Molmo"
|
||||
}),
|
||||
"prompt": ("STRING", {
|
||||
"multiline": True,
|
||||
"default": "Describe this image in detail.",
|
||||
"tooltip": "Instructions for the model. Be specific about what aspects of the image you want analyzed."
|
||||
}),
|
||||
"model_name": (list(MOLMO_MODELS.keys()), {
|
||||
"tooltip": "⚠️ WARNING: These are very large models requiring significant RAM/VRAM. Start with MolmoE-1B."
|
||||
}),
|
||||
"memory_mode": (list(MEMORY_MODES.keys()), {
|
||||
"default": "4-bit Quantized (15GB+ Required)",
|
||||
"tooltip": "Controls RAM/VRAM usage. Use most aggressive option that works on your system."
|
||||
}),
|
||||
"max_new_tokens": ("INT", {
|
||||
"default": 200,
|
||||
"min": 1,
|
||||
"max": 2048,
|
||||
"tooltip": "Maximum tokens to generate. Higher values need more VRAM. Start small (200) and increase if needed."
|
||||
}),
|
||||
"temperature": ("FLOAT", {
|
||||
"default": 0.7,
|
||||
"min": 0.1,
|
||||
"max": 2.0,
|
||||
"step": 0.1,
|
||||
"tooltip": "Controls randomness. Lower (0.1-0.5) = more focused, higher (0.8-2.0) = more creative."
|
||||
}),
|
||||
"top_p": ("FLOAT", {
|
||||
"default": 0.9,
|
||||
"min": 0.1,
|
||||
"max": 1.0,
|
||||
"step": 0.1,
|
||||
"tooltip": "Nucleus sampling. Lower = more focused on likely tokens, higher = more diverse vocabulary."
|
||||
}),
|
||||
"top_k": ("INT", {
|
||||
"default": 50,
|
||||
"min": 1,
|
||||
"max": 100,
|
||||
"tooltip": "Limits token choices to top K most likely. Lower = more focused, higher = more variety."
|
||||
}),
|
||||
"use_autocast": ("BOOLEAN", {
|
||||
"default": True,
|
||||
"tooltip": "Enables mixed precision. Keeps quality while reducing VRAM usage. Recommended ON."
|
||||
})
|
||||
}
|
||||
"image": ("IMAGE",),
|
||||
"prompt": (
|
||||
"STRING",
|
||||
{"multiline": True, "default": "Describe this image in detail."},
|
||||
),
|
||||
"model_name": (list(MOLMO_MODELS),),
|
||||
"memory_mode": (
|
||||
list(MEMORY_MODES),
|
||||
{"default": "4-bit Quantized (15GB+ Required)"},
|
||||
),
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 200, "min": 1, "max": 2048},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.2, "min": 0.0, "max": 2.0, "step": 0.1},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.9, "min": 0.01, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"top_k": ("INT", {"default": 50, "min": 1, "max": 100}),
|
||||
"use_autocast": ("BOOLEAN", {"default": True}),
|
||||
},
|
||||
"optional": {
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "generate"
|
||||
CATEGORY = "VLM Nodes/Molmo"
|
||||
|
||||
def generate(self, image, prompt, model_name, memory_mode="4-bit Quantized (15GB+ Required)",
|
||||
max_new_tokens=200, temperature=0.7, top_p=0.9, top_k=50, use_autocast=True):
|
||||
|
||||
def generate(
|
||||
self,
|
||||
image,
|
||||
prompt,
|
||||
model_name,
|
||||
memory_mode="4-bit Quantized (15GB+ Required)",
|
||||
max_new_tokens=200,
|
||||
temperature=0.2,
|
||||
top_p=0.9,
|
||||
top_k=50,
|
||||
use_autocast=True,
|
||||
unload_after=False,
|
||||
):
|
||||
predictor = self.get_or_create_model(
|
||||
(model_name, memory_mode, bool(use_autocast)),
|
||||
lambda: MolmoPredictor(model_name, memory_mode, use_autocast),
|
||||
)
|
||||
try:
|
||||
# Initialize or update predictor if needed
|
||||
if (self.predictor is None or
|
||||
self.current_model != model_name or
|
||||
self.current_memory_mode != memory_mode or
|
||||
self.current_autocast != use_autocast):
|
||||
|
||||
# Clean up old model if it exists
|
||||
if self.predictor is not None:
|
||||
del self.predictor.model
|
||||
del self.predictor.processor
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
self.predictor = MolmoPredictor(
|
||||
model_name,
|
||||
memory_mode=memory_mode,
|
||||
use_autocast=use_autocast
|
||||
)
|
||||
self.current_model = model_name
|
||||
self.current_memory_mode = memory_mode
|
||||
self.current_autocast = use_autocast
|
||||
|
||||
# Convert tensor to PIL Image
|
||||
pil_image = Image.fromarray((image[0] * 255).numpy().astype('uint8'))
|
||||
|
||||
# Generate response
|
||||
response = self.predictor.generate(
|
||||
pil_image,
|
||||
prompt,
|
||||
max_new_tokens=max_new_tokens,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
top_k=top_k
|
||||
return (
|
||||
batch_text(
|
||||
predictor.generate(
|
||||
pil,
|
||||
prompt,
|
||||
max_new_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
top_k,
|
||||
)
|
||||
for pil in tensor_batch_to_pil(image)
|
||||
),
|
||||
)
|
||||
|
||||
return (response,)
|
||||
|
||||
except Exception as e:
|
||||
# Clean up on error
|
||||
if hasattr(self, 'predictor') and self.predictor is not None:
|
||||
del self.predictor.model
|
||||
del self.predictor.processor
|
||||
self.predictor = None
|
||||
torch.cuda.empty_cache()
|
||||
return (f"Error: {str(e)}",)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
# Register the node
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"MolmoNode": MolmoNode
|
||||
}
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"MolmoNode": "Molmo Vision-Language Model"
|
||||
}
|
||||
NODE_CLASS_MAPPINGS = {"MolmoNode": MolmoNode}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"MolmoNode": "Molmo Vision-Language Model"}
|
||||
|
||||
@@ -1,2 +0,0 @@
|
||||
from .vision_encoder import VisionEncoder
|
||||
from .text_model import TextModel
|
||||
@@ -1,66 +0,0 @@
|
||||
# Copyright (c) Microsoft Corporation.
|
||||
# Licensed under the MIT license.
|
||||
|
||||
import math
|
||||
from typing import Optional
|
||||
|
||||
from transformers import PretrainedConfig
|
||||
|
||||
|
||||
class PhiConfig(PretrainedConfig):
|
||||
"""Phi configuration."""
|
||||
|
||||
model_type = "phi-msft"
|
||||
attribute_map = {
|
||||
"max_position_embeddings": "n_positions",
|
||||
"hidden_size": "n_embd",
|
||||
"num_attention_heads": "n_head",
|
||||
"num_hidden_layers": "n_layer",
|
||||
}
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
vocab_size: int = 50304,
|
||||
n_positions: int = 2048,
|
||||
n_embd: int = 1024,
|
||||
n_layer: int = 20,
|
||||
n_inner: Optional[int] = None,
|
||||
n_head: int = 16,
|
||||
n_head_kv: Optional[int] = None,
|
||||
rotary_dim: Optional[int] = 32,
|
||||
activation_function: Optional[str] = "gelu_new",
|
||||
flash_attn: bool = False,
|
||||
flash_rotary: bool = False,
|
||||
fused_dense: bool = False,
|
||||
attn_pdrop: float = 0.0,
|
||||
embd_pdrop: float = 0.0,
|
||||
resid_pdrop: float = 0.0,
|
||||
layer_norm_epsilon: float = 1e-5,
|
||||
initializer_range: float = 0.02,
|
||||
tie_word_embeddings: bool = False,
|
||||
pad_vocab_size_multiple: int = 64,
|
||||
gradient_checkpointing: bool = False,
|
||||
**kwargs
|
||||
) -> None:
|
||||
self.vocab_size = int(
|
||||
math.ceil(vocab_size / pad_vocab_size_multiple) * pad_vocab_size_multiple
|
||||
)
|
||||
self.n_positions = n_positions
|
||||
self.n_embd = n_embd
|
||||
self.n_layer = n_layer
|
||||
self.n_inner = n_inner
|
||||
self.n_head = n_head
|
||||
self.n_head_kv = n_head_kv
|
||||
self.rotary_dim = min(rotary_dim, n_embd // n_head)
|
||||
self.activation_function = activation_function
|
||||
self.flash_attn = flash_attn
|
||||
self.flash_rotary = flash_rotary
|
||||
self.fused_dense = fused_dense
|
||||
self.attn_pdrop = attn_pdrop
|
||||
self.embd_pdrop = embd_pdrop
|
||||
self.resid_pdrop = resid_pdrop
|
||||
self.layer_norm_epsilon = layer_norm_epsilon
|
||||
self.initializer_range = initializer_range
|
||||
self.gradient_checkpointing = gradient_checkpointing
|
||||
|
||||
super().__init__(tie_word_embeddings=tie_word_embeddings, **kwargs)
|
||||
File diff suppressed because it is too large
Load Diff
@@ -1,86 +0,0 @@
|
||||
import torch
|
||||
import transformers
|
||||
from transformers import CodeGenTokenizerFast as Tokenizer
|
||||
from accelerate import init_empty_weights, load_checkpoint_and_dispatch
|
||||
from .phi.configuration_phi import PhiConfig
|
||||
from .phi.modeling_phi import PhiForCausalLM
|
||||
import re
|
||||
|
||||
transformers.logging.set_verbosity_error()
|
||||
|
||||
|
||||
class TextModel:
|
||||
def __init__(self, model_path: str = "model") -> None:
|
||||
super().__init__()
|
||||
self.tokenizer = Tokenizer.from_pretrained(f"{model_path}/tokenizer")
|
||||
phi_config = PhiConfig.from_pretrained(f"{model_path}/text_model_cfg.json")
|
||||
|
||||
with init_empty_weights():
|
||||
self.model = PhiForCausalLM(phi_config)
|
||||
|
||||
self.model = load_checkpoint_and_dispatch(
|
||||
self.model,
|
||||
f"{model_path}/text_model.pt",
|
||||
device_map="auto",
|
||||
)
|
||||
|
||||
self.text_emb = self.model.get_input_embeddings()
|
||||
|
||||
def input_embeds(self, prompt, image_embeds):
|
||||
embeds = []
|
||||
|
||||
def _add_toks(toks):
|
||||
embeds.append(self.text_emb(toks))
|
||||
|
||||
def _tokenize(txt):
|
||||
return self.tokenizer(
|
||||
txt, return_tensors="pt", add_special_tokens=False
|
||||
).input_ids.to(self.model.device)
|
||||
|
||||
# Add BOS token
|
||||
_add_toks(
|
||||
torch.tensor([[self.tokenizer.bos_token_id]], device=self.model.device)
|
||||
)
|
||||
|
||||
if "<image>" not in prompt:
|
||||
embeds.append(self.text_emb(_tokenize(prompt)))
|
||||
else:
|
||||
assert prompt.count("<image>") == 1
|
||||
before, after = prompt.split("<image>")
|
||||
embeds.append(self.text_emb(_tokenize(f"{before}<image>")))
|
||||
embeds.append(image_embeds.to(self.model.device))
|
||||
embeds.append(self.text_emb(_tokenize(f"</image>{after}")))
|
||||
|
||||
return torch.cat(embeds, dim=1)
|
||||
|
||||
def generate(
|
||||
self, image_embeds, prompt, eos_text="Human:", max_new_tokens=128, **kwargs
|
||||
):
|
||||
eos_tokens = self.tokenizer(eos_text, add_special_tokens=False)[0].ids
|
||||
|
||||
generate_config = {
|
||||
"eos_token_id": eos_tokens,
|
||||
"bos_token_id": self.tokenizer.bos_token_id,
|
||||
"pad_token_id": self.tokenizer.eos_token_id,
|
||||
"max_new_tokens": max_new_tokens,
|
||||
**kwargs,
|
||||
}
|
||||
|
||||
with torch.no_grad():
|
||||
inputs_embeds = self.input_embeds(prompt, image_embeds)
|
||||
output_ids = self.model.generate(
|
||||
inputs_embeds=inputs_embeds, **generate_config
|
||||
)
|
||||
|
||||
return self.tokenizer.batch_decode(output_ids, skip_special_tokens=True)
|
||||
|
||||
def answer_question(self, image_embeds, question):
|
||||
prompt = f"<image>\n\nQuestion: {question}\n\nAnswer:"
|
||||
answer = self.generate(
|
||||
image_embeds,
|
||||
prompt,
|
||||
eos_text="<END>",
|
||||
max_new_tokens=128,
|
||||
)[0]
|
||||
|
||||
return re.sub("<$", "", re.sub("END$", "", answer)).strip()
|
||||
@@ -1,35 +0,0 @@
|
||||
import torch
|
||||
from PIL import Image
|
||||
from einops import rearrange
|
||||
from torchvision.transforms.v2 import (
|
||||
Compose,
|
||||
Resize,
|
||||
InterpolationMode,
|
||||
ToImage,
|
||||
ToDtype,
|
||||
Normalize,
|
||||
)
|
||||
|
||||
|
||||
|
||||
class VisionEncoder:
|
||||
def __init__(self, model_path: str = "model") -> None:
|
||||
self.model = torch.jit.load(f"{model_path}/vision.pt").to(dtype=torch.float32)
|
||||
self.preprocess = Compose(
|
||||
[
|
||||
Resize(size=(384, 384), interpolation=InterpolationMode.BICUBIC),
|
||||
ToImage(),
|
||||
ToDtype(torch.float32, scale=True),
|
||||
Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5]),
|
||||
]
|
||||
)
|
||||
|
||||
def __call__(self, image: Image) -> torch.Tensor:
|
||||
with torch.no_grad():
|
||||
image_vec = self.preprocess(image.convert("RGB")).unsqueeze(0)
|
||||
image_vec = image_vec[:, :, :-6, :-6]
|
||||
image_vec = rearrange(
|
||||
image_vec, "b c (h p1) (w p2) -> b (h w) (c p1 p2)", p1=14, p2=14
|
||||
)
|
||||
|
||||
return self.model(image_vec)
|
||||
+137
-41
@@ -1,43 +1,106 @@
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
from PIL import Image
|
||||
from pathlib import Path
|
||||
"""Current Moondream 2 node using the model's supported query API."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import torch
|
||||
from torchvision.transforms import ToPILImage
|
||||
from huggingface_hub import snapshot_download
|
||||
import folder_paths
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
inference_context,
|
||||
model_device,
|
||||
require_module,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
MODEL_ID = "vikhyatk/moondream2"
|
||||
MODEL_REVISION = "2025-06-21"
|
||||
|
||||
# Define the directory for saving files related to your new model
|
||||
files_for_moondream2 = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for_moondream2"
|
||||
files_for_moondream2.mkdir(parents=True, exist_ok=True) # Ensure the directory exists
|
||||
|
||||
class Moondream2Predictor:
|
||||
def __init__(self):
|
||||
self.model_path = snapshot_download("vikhyatk/moondream2",
|
||||
local_dir=files_for_moondream2,
|
||||
force_download=False, # Set to True if you always want to download, regardless of local copy
|
||||
local_files_only=False, # Set to False to allow downloading if not available locally
|
||||
revision="2024-04-02", # Specify the revision date for version control
|
||||
local_dir_use_symlinks="auto", # or set to True/False based on your symlink preference
|
||||
ignore_patterns=["*.bin", "*.jpg", "*.png", "*.gguf"]) # Customize based on need
|
||||
self.device = "cuda:0" if torch.cuda.is_available() else "cpu"
|
||||
self.model = AutoModelForCausalLM.from_pretrained(self.model_path, trust_remote_code=True).to(self.device).eval()
|
||||
self.tokenizer = AutoTokenizer.from_pretrained(self.model_path)
|
||||
transformers = require_module("transformers")
|
||||
dynamic_modules = require_module("transformers.dynamic_module_utils")
|
||||
model_path = snapshot_download(
|
||||
MODEL_ID,
|
||||
"moondream2",
|
||||
revision=MODEL_REVISION,
|
||||
ignore_patterns=["*.bin", "*.gguf"],
|
||||
)
|
||||
self.dtype = torch_dtype("bfloat16")
|
||||
config = transformers.AutoConfig.from_pretrained(
|
||||
model_path,
|
||||
revision=MODEL_REVISION,
|
||||
trust_remote_code=True,
|
||||
)
|
||||
remote_class = dynamic_modules.get_class_from_dynamic_module(
|
||||
"hf_moondream.HfMoondream",
|
||||
model_path,
|
||||
local_files_only=True,
|
||||
)
|
||||
|
||||
def generate_predictions(self, image_path, question):
|
||||
# Load and process the image
|
||||
image_input = Image.open(image_path).convert("RGB")
|
||||
enc_image = self.model.encode_image(image_input)
|
||||
class Transformers5Moondream(remote_class):
|
||||
def __init__(self, model_config):
|
||||
super().__init__(model_config)
|
||||
# The pinned remote wrapper predates the Transformers 5 model
|
||||
# loader and does not declare its tied-weight metadata. Calling
|
||||
# the full post_init would reinitialize custom Moondream state.
|
||||
self.all_tied_weights_keys = {}
|
||||
|
||||
# Generate predictions
|
||||
generated_text = self.model.answer_question(enc_image, question, self.tokenizer)
|
||||
model = Transformers5Moondream.from_pretrained(
|
||||
model_path,
|
||||
config=config,
|
||||
dtype=self.dtype,
|
||||
)
|
||||
model.eval()
|
||||
self.handle = ManagedTorchModel(model)
|
||||
|
||||
return generated_text
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
|
||||
class Moondream2model:
|
||||
def __init__(self):
|
||||
self.predictor = Moondream2Predictor()
|
||||
def generate(
|
||||
self,
|
||||
images,
|
||||
question,
|
||||
max_tokens=256,
|
||||
temperature=0.0,
|
||||
top_p=0.3,
|
||||
reasoning=False,
|
||||
):
|
||||
results = []
|
||||
for image in tensor_batch_to_pil(images):
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
response = model.query(
|
||||
image,
|
||||
question,
|
||||
reasoning=bool(reasoning),
|
||||
settings={
|
||||
"max_tokens": int(max_tokens),
|
||||
"temperature": float(temperature),
|
||||
"top_p": float(top_p),
|
||||
# Moondream's encoder indexes this optional key
|
||||
# directly; None selects the base checkpoint.
|
||||
"variant": None,
|
||||
},
|
||||
)
|
||||
if isinstance(response, dict):
|
||||
response = response.get("answer", response)
|
||||
if not str(response).strip():
|
||||
raise RuntimeError(
|
||||
"Moondream2 returned an empty response on this "
|
||||
"Torch/Transformers build. Use the Modern VLM node with "
|
||||
"LFM2.5-VL 450M, InternVL 3.5 1B, or Qwen3-VL 2B."
|
||||
)
|
||||
results.append(str(response))
|
||||
return batch_text(results)
|
||||
|
||||
|
||||
class Moondream2model(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
@@ -47,26 +110,59 @@ class Moondream2model:
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "",
|
||||
"default": "Describe this image in detail.",
|
||||
},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"max_tokens": (
|
||||
"INT",
|
||||
{"default": 256, "min": 1, "max": 2048},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.0, "min": 0.0, "max": 2.0, "step": 0.05},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.3, "min": 0.01, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"reasoning": ("BOOLEAN", {"default": False}),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
|
||||
FUNCTION = "moondream2_generate_predictions"
|
||||
|
||||
CATEGORY = "VLM Nodes/Moondream2"
|
||||
|
||||
def moondream2_generate_predictions(self, image, text_input):
|
||||
# Convert tensor image to PIL Image
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
temp_path = files_for_moondream2 / "temp_image.png"
|
||||
pil_image.save(temp_path)
|
||||
|
||||
response = self.predictor.generate_predictions(temp_path, text_input)
|
||||
return (response, )
|
||||
def moondream2_generate_predictions(
|
||||
self,
|
||||
image,
|
||||
text_input,
|
||||
max_tokens=256,
|
||||
temperature=0.0,
|
||||
top_p=0.3,
|
||||
reasoning=False,
|
||||
unload_after=False,
|
||||
):
|
||||
predictor = self.get_or_create_model(
|
||||
(MODEL_ID, MODEL_REVISION), Moondream2Predictor
|
||||
)
|
||||
try:
|
||||
return (
|
||||
predictor.generate(
|
||||
image,
|
||||
text_input,
|
||||
max_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
reasoning,
|
||||
),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"Moondream2model": Moondream2model}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Moondream2model": "Moondream-2 Node"}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Moondream2model": "Moondream 2"}
|
||||
|
||||
+17
-62
@@ -1,38 +1,10 @@
|
||||
from .moondream import VisionEncoder, TextModel
|
||||
from huggingface_hub import snapshot_download
|
||||
import torch
|
||||
import os
|
||||
import hashlib
|
||||
from torchvision import transforms
|
||||
from pathlib import Path
|
||||
import folder_paths
|
||||
"""Backward-compatible MoonDream node powered by the current Moondream 2."""
|
||||
|
||||
if torch.cuda.is_available():
|
||||
DEVICE = "cuda"
|
||||
DTYPE = torch.float16
|
||||
else:
|
||||
DEVICE = "cpu"
|
||||
DTYPE = torch.float32
|
||||
from .moondream2 import MODEL_ID, MODEL_REVISION, Moondream2Predictor
|
||||
from .runtime import CachedModelNode
|
||||
|
||||
|
||||
files_for_moondream = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for__moondream"
|
||||
files_for_moondream.mkdir(parents=True, exist_ok=True)
|
||||
output_directory = os.path.join(files_for_moondream , "output")
|
||||
# Define your local directory where you want to save the files
|
||||
|
||||
image_encoder_cache_path = os.path.join(output_directory, "image_encoder_cache")
|
||||
class MoonDream:
|
||||
def __init__(self):
|
||||
self.model_path = snapshot_download("vikhyatk/moondream1",
|
||||
revision="5cd8d1ecd7e0d8d95222543e1960d340ddffbfef",
|
||||
local_dir=files_for_moondream,
|
||||
force_download=False, # Set to True if you always want to download, regardless of local copy
|
||||
local_files_only=False, # Set to False to allow downloading if not available locally
|
||||
local_dir_use_symlinks="auto" # or set to True/False based on your symlink preference
|
||||
)
|
||||
self.vision_encoder = VisionEncoder(self.model_path)
|
||||
self.text_model = TextModel(self.model_path)
|
||||
|
||||
class MoonDream(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
@@ -42,45 +14,28 @@ class MoonDream:
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "",
|
||||
"default": "Describe this image in detail.",
|
||||
},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"unload_after": ("BOOLEAN", {"default": False})
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
|
||||
FUNCTION = "answer_questions"
|
||||
|
||||
CATEGORY = "VLM Nodes/MoonDream"
|
||||
|
||||
def process_image(self, image):
|
||||
# Calculate checksum of the image
|
||||
|
||||
image_array = image.numpy() # Convert Tensor to NumPy array
|
||||
image_hash = hashlib.sha256(image_array.tobytes()).hexdigest()
|
||||
image = transforms.ToPILImage()(image[0].permute(2, 0, 1))
|
||||
# Check if `image_encoder_cache/{image_hash}.pt` exists, if so load and return it.
|
||||
# Otherwise, save the encoded image to `image_encoder_cache/{image_hash}.pt` and return it.
|
||||
cache_path = f"{image_encoder_cache_path}/{image_hash}.pt"
|
||||
if os.path.exists(cache_path):
|
||||
return torch.load(cache_path).to(DEVICE, dtype=DTYPE)
|
||||
else:
|
||||
image_vec = self.vision_encoder(image)
|
||||
os.makedirs(image_encoder_cache_path, exist_ok=True)
|
||||
torch.save(image_vec, cache_path)
|
||||
return image_vec.to(DEVICE, dtype=DTYPE)
|
||||
|
||||
def answer_questions(self, image, question):
|
||||
image_embeds = self.process_image(image)
|
||||
full_sentence = self.text_model.answer_question(image_embeds, question)
|
||||
return (full_sentence,)
|
||||
def answer_questions(self, image, question, unload_after=False):
|
||||
predictor = self.get_or_create_model(
|
||||
(MODEL_ID, MODEL_REVISION), Moondream2Predictor
|
||||
)
|
||||
try:
|
||||
return (predictor.generate(image, question),)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
# A dictionary that contains all nodes you want to export with their names
|
||||
NODE_CLASS_MAPPINGS = {"MoonDream": MoonDream}
|
||||
|
||||
# A dictionary that contains the friendly/humanly readable titles for the nodes
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"MoonDream": "MoonDream Node"}
|
||||
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"MoonDream": "MoonDream (Moondream 2)"}
|
||||
|
||||
+350
-792
File diff suppressed because it is too large
Load Diff
+3
-3
@@ -14,8 +14,8 @@ class PlayMusic:
|
||||
return {"required": {
|
||||
"mode": (["always", "on empty queue"], {}),
|
||||
"volume": ("FLOAT", {"min": 0, "max": 1, "step": 0.1, "default": 0.5}),
|
||||
"wave_form": ([], {"forceInput": True}),
|
||||
"sample_rate": ("INT", {"forceInput": True}),
|
||||
"wave_form": (any,),
|
||||
"sample_rate": ("INT",),
|
||||
}}
|
||||
|
||||
FUNCTION = "nop"
|
||||
@@ -30,7 +30,7 @@ class PlayMusic:
|
||||
return float("NaN")
|
||||
|
||||
def nop(self, mode, volume, wave_form, sample_rate):
|
||||
return {"ui": {"a": wave_form, "b": sample_rate}, "result": (any,)}
|
||||
return {"ui": {"a": wave_form, "b": sample_rate}, "result": (wave_form,)}
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
|
||||
+371
-366
@@ -1,409 +1,414 @@
|
||||
"""Qwen2-VL with real image/video batches and ComfyUI-aware VRAM handling."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
import psutil
|
||||
import os
|
||||
from PIL import Image
|
||||
from pathlib import Path
|
||||
from torchvision.transforms import ToPILImage
|
||||
from huggingface_hub import snapshot_download
|
||||
import folder_paths
|
||||
from transformers import AutoModelForVision2Seq, AutoTokenizer, AutoProcessor, BitsAndBytesConfig
|
||||
from qwen_vl_utils import process_vision_info
|
||||
|
||||
def check_flash_attention():
|
||||
"""Check if flash attention 2 is available"""
|
||||
try:
|
||||
from flash_attn import flash_attn_func
|
||||
return True
|
||||
except ImportError:
|
||||
return False
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ExternalTorchModel,
|
||||
ManagedTorchModel,
|
||||
accelerator_backend,
|
||||
batch_text,
|
||||
execution_device,
|
||||
external_device_map,
|
||||
inference_context,
|
||||
model_device,
|
||||
move_inputs,
|
||||
require_quantization_backend,
|
||||
require_module,
|
||||
reserve_external_vram,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
FLASH_ATTENTION_AVAILABLE = check_flash_attention()
|
||||
|
||||
# Define the directory for saving Qwen2-VL files
|
||||
files_for_qwen2vl = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for_qwen2vl"
|
||||
files_for_qwen2vl.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
# Model VRAM requirements (approximate, in GB)
|
||||
MODEL_VRAM_REQUIREMENTS = {
|
||||
"Qwen2-VL-2B": 4,
|
||||
"Qwen2-VL-7B": 14,
|
||||
"Qwen2-VL-72B": 40,
|
||||
"Qwen2-VL-2B-AWQ": 2,
|
||||
"Qwen2-VL-2B-GPTQ-Int4": 2,
|
||||
"Qwen2-VL-2B-GPTQ-Int8": 3,
|
||||
"Qwen2-VL-7B-AWQ": 5,
|
||||
"Qwen2-VL-7B-GPTQ-Int4": 5,
|
||||
"Qwen2-VL-7B-GPTQ-Int8": 8,
|
||||
"Qwen2-VL-72B-AWQ": 20,
|
||||
"Qwen2-VL-72B-GPTQ-Int4": 20,
|
||||
"Qwen2-VL-72B-GPTQ-Int8": 25,
|
||||
}
|
||||
|
||||
QWEN2_VL_MODELS = {
|
||||
"Qwen2-VL-2B": "Qwen/Qwen2-VL-2B-Instruct",
|
||||
"Qwen2-VL-7B": "Qwen/Qwen2-VL-7B-Instruct",
|
||||
"Qwen2-VL-72B": "Qwen/Qwen2-VL-72B-Instruct",
|
||||
"Qwen2-VL-2B-AWQ": "Qwen/Qwen2-VL-2B-Instruct-AWQ",
|
||||
"Qwen2-VL-2B-GPTQ-Int4": "Qwen/Qwen2-VL-2B-Instruct-GPTQ-Int4",
|
||||
"Qwen2-VL-2B-GPTQ-Int8": "Qwen/Qwen2-VL-2B-Instruct-GPTQ-Int8",
|
||||
"Qwen2-VL-7B-AWQ": "Qwen/Qwen2-VL-7B-Instruct-AWQ",
|
||||
"Qwen2-VL-7B-GPTQ-Int4": "Qwen/Qwen2-VL-7B-Instruct-GPTQ-Int4",
|
||||
"Qwen2-VL-7B-GPTQ-Int8": "Qwen/Qwen2-VL-7B-Instruct-GPTQ-Int8",
|
||||
"Qwen2-VL-72B-AWQ": "Qwen/Qwen2-VL-72B-Instruct-AWQ",
|
||||
"Qwen2-VL-72B-GPTQ-Int4": "Qwen/Qwen2-VL-72B-Instruct-GPTQ-Int4",
|
||||
"Qwen2-VL-72B-GPTQ-Int8": "Qwen/Qwen2-VL-72B-Instruct-GPTQ-Int8",
|
||||
}
|
||||
# Old workflows used separate AWQ/GPTQ repositories whose integration breaks
|
||||
# across Transformers/AutoGPTQ releases. Resolve those labels to the same base
|
||||
# weights and the maintained bitsandbytes path instead.
|
||||
LEGACY_QUANTIZED_ALIASES = {
|
||||
f"Qwen2-VL-{size}-{quant}": (
|
||||
f"Qwen2-VL-{size}",
|
||||
(
|
||||
"Balanced (8-bit)"
|
||||
if quant.endswith("Int8")
|
||||
else "Maximum Savings (4-bit)"
|
||||
),
|
||||
)
|
||||
for size in ("2B", "7B", "72B")
|
||||
for quant in ("AWQ", "GPTQ-Int4", "GPTQ-Int8")
|
||||
}
|
||||
QWEN2_VL_CHOICES = ("Qwen2-VL-2B", "Qwen2-VL-7B")
|
||||
|
||||
MEMORY_MODES = [
|
||||
"ComfyUI managed (BF16)",
|
||||
"Balanced (8-bit)",
|
||||
"Maximum Savings (4-bit)",
|
||||
"CPU Offload",
|
||||
"Default",
|
||||
]
|
||||
|
||||
ESTIMATED_MODEL_BYTES = {
|
||||
"Qwen2-VL-2B": 5 * 1024**3,
|
||||
"Qwen2-VL-7B": 16 * 1024**3,
|
||||
"Qwen2-VL-72B": 145 * 1024**3,
|
||||
}
|
||||
|
||||
MEMORY_EFFICIENT_CONFIGS = {
|
||||
"Balanced (8-bit)": {
|
||||
"load_in_8bit": True,
|
||||
"load_in_4bit": False,
|
||||
"cpu_offload": False,
|
||||
"attention_mode": "flash_attention_2" if FLASH_ATTENTION_AVAILABLE else None,
|
||||
},
|
||||
"Maximum Savings (4-bit)": {
|
||||
"load_in_8bit": False,
|
||||
"load_in_4bit": True,
|
||||
"cpu_offload": True,
|
||||
"attention_mode": "flash_attention_2" if FLASH_ATTENTION_AVAILABLE else None,
|
||||
},
|
||||
"CPU Offload": {
|
||||
"load_in_8bit": False,
|
||||
"load_in_4bit": False,
|
||||
"cpu_offload": True,
|
||||
"attention_mode": None,
|
||||
},
|
||||
"Default": {
|
||||
"load_in_8bit": False,
|
||||
"load_in_4bit": False,
|
||||
"cpu_offload": False,
|
||||
"attention_mode": None,
|
||||
}
|
||||
}
|
||||
|
||||
class SystemResources:
|
||||
@staticmethod
|
||||
def get_available_memory():
|
||||
"""Get available system memory in GB"""
|
||||
return psutil.virtual_memory().available / (1024 * 1024 * 1024)
|
||||
def _model_class(transformers):
|
||||
for name in (
|
||||
"Qwen2VLForConditionalGeneration",
|
||||
"AutoModelForImageTextToText",
|
||||
"AutoModelForMultimodalLM",
|
||||
):
|
||||
cls = getattr(transformers, name, None)
|
||||
if cls is not None:
|
||||
return cls
|
||||
raise RuntimeError(
|
||||
"This Transformers version does not include a Qwen2-VL model class."
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def get_available_vram():
|
||||
"""Get available VRAM in GB"""
|
||||
if not torch.cuda.is_available():
|
||||
return 0
|
||||
|
||||
try:
|
||||
torch.cuda.empty_cache() # Clear unused cached memory
|
||||
return torch.cuda.get_device_properties(0).total_memory / (1024 * 1024 * 1024)
|
||||
except:
|
||||
return 0
|
||||
|
||||
@staticmethod
|
||||
def check_resources(model_name, memory_mode):
|
||||
"""Check if system has enough resources for the model"""
|
||||
required_vram = MODEL_VRAM_REQUIREMENTS.get(model_name, 0)
|
||||
config = MEMORY_EFFICIENT_CONFIGS[memory_mode]
|
||||
|
||||
# Adjust VRAM requirements based on memory mode
|
||||
if config["load_in_8bit"]:
|
||||
required_vram = required_vram * 0.5 # Approximately half VRAM usage
|
||||
elif config["load_in_4bit"]:
|
||||
required_vram = required_vram * 0.25 # Approximately quarter VRAM usage
|
||||
elif config["cpu_offload"]:
|
||||
required_vram = required_vram * 0.7 # Rough estimate for CPU offloading
|
||||
|
||||
available_vram = SystemResources.get_available_vram()
|
||||
available_memory = SystemResources.get_available_memory()
|
||||
|
||||
# Need at least 2GB system memory buffer
|
||||
required_system_memory = required_vram + 2
|
||||
|
||||
error_messages = []
|
||||
if available_vram < required_vram:
|
||||
error_messages.append(
|
||||
f"Insufficient VRAM: Model {model_name} requires {required_vram:.1f}GB VRAM, "
|
||||
f"but only {available_vram:.1f}GB available. "
|
||||
"Try using a more aggressive memory saving mode."
|
||||
)
|
||||
|
||||
if available_memory < required_system_memory:
|
||||
error_messages.append(
|
||||
f"Insufficient system memory: Need at least {required_system_memory:.1f}GB, "
|
||||
f"but only {available_memory:.1f}GB available"
|
||||
)
|
||||
|
||||
return error_messages
|
||||
def _attention_value(mode: str) -> str:
|
||||
return {
|
||||
"Auto (SDPA)": "sdpa",
|
||||
"Flash Attention 2": "flash_attention_2",
|
||||
"Eager": "eager",
|
||||
}[mode]
|
||||
|
||||
|
||||
class Qwen2VLPredictor:
|
||||
def __init__(self, model_name, memory_mode="Balanced (8-bit)"):
|
||||
# Check system resources
|
||||
error_messages = SystemResources.check_resources(model_name, memory_mode)
|
||||
if error_messages:
|
||||
raise RuntimeError("\n".join(error_messages))
|
||||
|
||||
self.model_path = snapshot_download(
|
||||
QWEN2_VL_MODELS[model_name],
|
||||
local_dir=files_for_qwen2vl / model_name,
|
||||
force_download=False,
|
||||
local_files_only=False,
|
||||
revision="main"
|
||||
)
|
||||
|
||||
self.device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
|
||||
try:
|
||||
# Get memory configuration
|
||||
config = MEMORY_EFFICIENT_CONFIGS[memory_mode]
|
||||
|
||||
# Base model kwargs
|
||||
model_kwargs = {
|
||||
"trust_remote_code": True,
|
||||
"device_map": "auto" if config["cpu_offload"] else None,
|
||||
}
|
||||
|
||||
# Setup quantization config if needed
|
||||
if config["load_in_8bit"] or config["load_in_4bit"]:
|
||||
model_kwargs.update({
|
||||
"load_in_8bit": config["load_in_8bit"],
|
||||
"load_in_4bit": config["load_in_4bit"],
|
||||
"bnb_4bit_compute_dtype": torch.float16,
|
||||
"bnb_4bit_use_double_quant": True,
|
||||
})
|
||||
|
||||
# Add attention optimization if specified and available
|
||||
if config["attention_mode"]:
|
||||
try:
|
||||
model_kwargs["attn_implementation"] = config["attention_mode"]
|
||||
except Exception as e:
|
||||
print(f"Warning: Flash Attention 2 requested but not available: {str(e)}")
|
||||
|
||||
# Set appropriate dtype based on model type
|
||||
if "GPTQ" in model_name or "AWQ" in model_name:
|
||||
model_kwargs["torch_dtype"] = "auto"
|
||||
else:
|
||||
model_kwargs["torch_dtype"] = torch.float16 if torch.cuda.is_available() else torch.float32
|
||||
|
||||
self.model = AutoModelForVision2Seq.from_pretrained(
|
||||
self.model_path,
|
||||
**model_kwargs
|
||||
def __init__(
|
||||
self,
|
||||
model_name: str,
|
||||
memory_mode: str,
|
||||
attention_mode: str,
|
||||
min_pixels: int,
|
||||
max_pixels: int,
|
||||
):
|
||||
transformers = require_module("transformers")
|
||||
if model_name in LEGACY_QUANTIZED_ALIASES:
|
||||
model_name, memory_mode = LEGACY_QUANTIZED_ALIASES[model_name]
|
||||
if (
|
||||
attention_mode == "Flash Attention 2"
|
||||
and accelerator_backend(execution_device())
|
||||
not in {"nvidia-cuda", "amd-rocm"}
|
||||
):
|
||||
raise RuntimeError(
|
||||
"Flash Attention 2 requires a supported CUDA or ROCm build. "
|
||||
"Select Auto (SDPA) on Apple Metal, Intel XPU, or CPU."
|
||||
)
|
||||
|
||||
self.processor = AutoProcessor.from_pretrained(self.model_path)
|
||||
self.tokenizer = AutoTokenizer.from_pretrained(self.model_path, trust_remote_code=True)
|
||||
|
||||
except RuntimeError as e:
|
||||
if "out of memory" in str(e):
|
||||
process = psutil.Process()
|
||||
mem_info = process.memory_info()
|
||||
torch.cuda.empty_cache()
|
||||
if memory_mode in {"Balanced (8-bit)", "Maximum Savings (4-bit)"}:
|
||||
# Validate before downloading a multi-gigabyte checkpoint.
|
||||
require_quantization_backend(memory_mode)
|
||||
repo_id = QWEN2_VL_MODELS[model_name]
|
||||
model_path = snapshot_download(
|
||||
repo_id,
|
||||
f"qwen2vl/{model_name}",
|
||||
ignore_patterns=["*.bin"],
|
||||
)
|
||||
self.dtype = torch_dtype("bfloat16")
|
||||
self.processor = transformers.AutoProcessor.from_pretrained(
|
||||
model_path,
|
||||
min_pixels=int(min_pixels),
|
||||
max_pixels=int(max_pixels),
|
||||
)
|
||||
kwargs: dict[str, Any] = {
|
||||
"torch_dtype": self.dtype,
|
||||
"attn_implementation": _attention_value(attention_mode),
|
||||
}
|
||||
external = memory_mode in {
|
||||
"Balanced (8-bit)",
|
||||
"Maximum Savings (4-bit)",
|
||||
"CPU Offload",
|
||||
}
|
||||
|
||||
if memory_mode in {"Balanced (8-bit)", "Maximum Savings (4-bit)"}:
|
||||
kwargs["quantization_config"] = transformers.BitsAndBytesConfig(
|
||||
load_in_8bit=memory_mode == "Balanced (8-bit)",
|
||||
load_in_4bit=memory_mode == "Maximum Savings (4-bit)",
|
||||
bnb_4bit_compute_dtype=self.dtype,
|
||||
bnb_4bit_quant_type="nf4",
|
||||
bnb_4bit_use_double_quant=True,
|
||||
)
|
||||
if external:
|
||||
require_module("accelerate")
|
||||
estimate = ESTIMATED_MODEL_BYTES.get(
|
||||
model_name.split("-AWQ", 1)[0].split("-GPTQ", 1)[0],
|
||||
8 * 1024**3,
|
||||
)
|
||||
reserve_external_vram(
|
||||
estimate // (4 if memory_mode == "Maximum Savings (4-bit)" else 2)
|
||||
)
|
||||
kwargs["device_map"] = external_device_map(
|
||||
allow_auto_offload=memory_mode == "CPU Offload"
|
||||
)
|
||||
|
||||
try:
|
||||
model = _model_class(transformers).from_pretrained(
|
||||
model_path, **kwargs
|
||||
).eval()
|
||||
except ImportError as exc:
|
||||
if attention_mode == "Flash Attention 2":
|
||||
raise RuntimeError(
|
||||
f"Out of VRAM while loading {model_name}. Try:\n"
|
||||
"1. Using a more aggressive memory saving mode\n"
|
||||
"2. Using a smaller model (e.g., 2B instead of 7B)\n"
|
||||
"3. Using a quantized version (AWQ/GPTQ)\n"
|
||||
"4. Clearing other models from memory\n"
|
||||
"5. Restarting ComfyUI\n"
|
||||
f"Process memory: {mem_info.rss / 1024**3:.1f}GB"
|
||||
) from e
|
||||
"Flash Attention 2 was selected but flash-attn is not "
|
||||
"installed for this PyTorch accelerator build. Use Auto "
|
||||
"(SDPA), or install a matching flash-attn wheel."
|
||||
) from exc
|
||||
raise
|
||||
|
||||
def process_video(self, video_frames, fps=1.0):
|
||||
"""Process video frames for video understanding"""
|
||||
|
||||
self.handle = (
|
||||
ExternalTorchModel(model, processor=self.processor)
|
||||
if external
|
||||
else ManagedTorchModel(model, processor=self.processor)
|
||||
)
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
def _generate_messages(
|
||||
self,
|
||||
messages,
|
||||
*,
|
||||
max_new_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
) -> str:
|
||||
process_vision_info = require_module(
|
||||
"qwen_vl_utils", "qwen-vl-utils"
|
||||
).process_vision_info
|
||||
text = self.processor.apply_chat_template(
|
||||
messages, tokenize=False, add_generation_prompt=True
|
||||
)
|
||||
image_inputs, video_inputs = process_vision_info(messages)
|
||||
inputs = self.processor(
|
||||
text=[text],
|
||||
images=image_inputs,
|
||||
videos=video_inputs,
|
||||
padding=True,
|
||||
return_tensors="pt",
|
||||
)
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
inputs = move_inputs(inputs, device)
|
||||
generation: dict[str, Any] = {
|
||||
"max_new_tokens": int(max_new_tokens),
|
||||
"do_sample": float(temperature) > 0.0,
|
||||
}
|
||||
if generation["do_sample"]:
|
||||
generation.update(
|
||||
temperature=float(temperature), top_p=float(top_p)
|
||||
)
|
||||
tokenizer = getattr(self.processor, "tokenizer", None)
|
||||
if tokenizer is not None:
|
||||
generation["pad_token_id"] = tokenizer.pad_token_id
|
||||
generation["eos_token_id"] = tokenizer.eos_token_id
|
||||
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
output_ids = model.generate(**inputs, **generation)
|
||||
trimmed = [
|
||||
output[len(input_ids) :]
|
||||
for input_ids, output in zip(inputs["input_ids"], output_ids)
|
||||
]
|
||||
return self.processor.batch_decode(
|
||||
trimmed,
|
||||
skip_special_tokens=True,
|
||||
clean_up_tokenization_spaces=False,
|
||||
)[0].strip()
|
||||
|
||||
def generate_images(
|
||||
self, images, prompt, max_new_tokens, temperature, top_p
|
||||
) -> str:
|
||||
results = []
|
||||
for image in tensor_batch_to_pil(images):
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "image", "image": image},
|
||||
{"type": "text", "text": prompt},
|
||||
],
|
||||
}
|
||||
]
|
||||
results.append(
|
||||
self._generate_messages(
|
||||
messages,
|
||||
max_new_tokens=max_new_tokens,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
)
|
||||
)
|
||||
return batch_text(results)
|
||||
|
||||
def generate_video(
|
||||
self,
|
||||
primary_image,
|
||||
frames,
|
||||
prompt,
|
||||
max_new_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
fps,
|
||||
) -> str:
|
||||
# The still IMAGE socket is required by ComfyUI for backwards
|
||||
# compatibility, but a connected frame batch is the visual source for
|
||||
# video inference. Mixing both causes small VLMs to answer from the
|
||||
# still and ignore temporal content.
|
||||
del primary_image
|
||||
frame_list = tensor_batch_to_pil(frames)
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "video",
|
||||
"video": video_frames,
|
||||
"fps": fps
|
||||
}
|
||||
]
|
||||
"video": frame_list,
|
||||
"fps": float(fps),
|
||||
},
|
||||
{
|
||||
"type": "text",
|
||||
"text": (
|
||||
f"The video frames are sampled at {float(fps):g} "
|
||||
f"FPS.\n\n{prompt}"
|
||||
),
|
||||
},
|
||||
],
|
||||
}
|
||||
]
|
||||
return messages
|
||||
|
||||
def generate_predictions(self, image_path, prompt, max_new_tokens=512, temperature=0.7, top_p=0.9, video_frames=None, fps=1.0):
|
||||
try:
|
||||
# Handle video input if provided
|
||||
if video_frames:
|
||||
messages = self.process_video(video_frames, fps)
|
||||
messages[0]["content"].append({"type": "text", "text": prompt})
|
||||
else:
|
||||
# Standard image processing
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "image", "image": str(image_path)},
|
||||
{"type": "text", "text": prompt}
|
||||
]
|
||||
}
|
||||
]
|
||||
|
||||
# Process the inputs
|
||||
text = self.processor.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
|
||||
image_inputs, video_inputs = process_vision_info(messages)
|
||||
|
||||
inputs = self.processor(
|
||||
text=[text],
|
||||
images=image_inputs,
|
||||
videos=video_inputs,
|
||||
return_tensors="pt",
|
||||
padding=True
|
||||
)
|
||||
|
||||
try:
|
||||
inputs = {k: v.to(self.device) for k, v in inputs.items()}
|
||||
|
||||
# Generate response
|
||||
output_ids = self.model.generate(
|
||||
**inputs,
|
||||
max_new_tokens=max_new_tokens,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
pad_token_id=self.tokenizer.pad_token_id,
|
||||
eos_token_id=self.tokenizer.eos_token_id
|
||||
)
|
||||
|
||||
# Decode and return the response
|
||||
generated_text = self.tokenizer.decode(output_ids[0][inputs["input_ids"].shape[1]:], skip_special_tokens=True)
|
||||
return generated_text.strip()
|
||||
|
||||
except RuntimeError as e:
|
||||
if "out of memory" in str(e):
|
||||
torch.cuda.empty_cache()
|
||||
raise RuntimeError(
|
||||
"Out of VRAM during generation. Try:\n"
|
||||
"1. Using a more aggressive memory saving mode\n"
|
||||
"2. Reducing max_new_tokens\n"
|
||||
"3. Using a smaller model\n"
|
||||
"4. Using a quantized version (AWQ/GPTQ)"
|
||||
) from e
|
||||
raise
|
||||
|
||||
except Exception as e:
|
||||
return f"Error during generation: {str(e)}"
|
||||
return self._generate_messages(
|
||||
messages,
|
||||
max_new_tokens=max_new_tokens,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
)
|
||||
|
||||
class Qwen2VLNode:
|
||||
def __init__(self):
|
||||
self.predictor = None
|
||||
self.current_model = None
|
||||
self.current_memory_mode = None
|
||||
|
||||
|
||||
class Qwen2VLNode(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"text_input": ("STRING", {
|
||||
"multiline": True,
|
||||
"default": "Describe this image in detail."
|
||||
}),
|
||||
"model_name": (list(QWEN2_VL_MODELS.keys()),),
|
||||
"memory_mode": (list(MEMORY_EFFICIENT_CONFIGS.keys()),),
|
||||
"max_new_tokens": ("INT", {
|
||||
"default": 512,
|
||||
"min": 1,
|
||||
"max": 2048
|
||||
}),
|
||||
"temperature": ("FLOAT", {
|
||||
"default": 0.7,
|
||||
"min": 0.1,
|
||||
"max": 2.0,
|
||||
"step": 0.1
|
||||
}),
|
||||
"top_p": ("FLOAT", {
|
||||
"default": 0.9,
|
||||
"min": 0.1,
|
||||
"max": 1.0,
|
||||
"step": 0.1
|
||||
})
|
||||
"text_input": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "Describe this image in detail.",
|
||||
},
|
||||
),
|
||||
"model_name": (list(QWEN2_VL_CHOICES),),
|
||||
"memory_mode": (
|
||||
MEMORY_MODES,
|
||||
{"default": "ComfyUI managed (BF16)"},
|
||||
),
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 512, "min": 1, "max": 8192},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.2, "min": 0.0, "max": 2.0, "step": 0.1},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.9, "min": 0.0, "max": 1.0, "step": 0.05},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"image": ("IMAGE",),
|
||||
"video_frames": ("IMAGE",),
|
||||
"fps": ("FLOAT", {
|
||||
"default": 1.0,
|
||||
"min": 0.1,
|
||||
"max": 30.0,
|
||||
"step": 0.1
|
||||
})
|
||||
}
|
||||
"fps": (
|
||||
"FLOAT",
|
||||
{"default": 1.0, "min": 0.1, "max": 60.0, "step": 0.1},
|
||||
),
|
||||
"attention_mode": (
|
||||
["Auto (SDPA)", "Flash Attention 2", "Eager"],
|
||||
{"default": "Auto (SDPA)"},
|
||||
),
|
||||
"min_pixels": (
|
||||
"INT",
|
||||
{"default": 256 * 28 * 28, "min": 28 * 28},
|
||||
),
|
||||
"max_pixels": (
|
||||
"INT",
|
||||
{"default": 1280 * 28 * 28, "min": 28 * 28},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "generate"
|
||||
CATEGORY = "VLM Nodes/Qwen2-VL"
|
||||
|
||||
def generate(self, image, text_input, model_name, memory_mode="Balanced (8-bit)",
|
||||
max_new_tokens=512, temperature=0.7, top_p=0.9, video_frames=None, fps=1.0):
|
||||
# Initialize or update predictor if model or memory mode changed
|
||||
if (self.predictor is None or self.current_model != model_name or
|
||||
self.current_memory_mode != memory_mode):
|
||||
|
||||
# Clean up old model
|
||||
if self.predictor is not None:
|
||||
del self.predictor.model
|
||||
del self.predictor.processor
|
||||
del self.predictor.tokenizer
|
||||
torch.cuda.empty_cache()
|
||||
|
||||
try:
|
||||
self.predictor = Qwen2VLPredictor(model_name, memory_mode)
|
||||
self.current_model = model_name
|
||||
self.current_memory_mode = memory_mode
|
||||
except Exception as e:
|
||||
return (f"Error initializing model: {str(e)}",)
|
||||
|
||||
# Convert tensor image to PIL Image and save temporarily
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
temp_path = files_for_qwen2vl / "temp_image.png"
|
||||
pil_image.save(temp_path)
|
||||
|
||||
video_frame_list = None
|
||||
if video_frames is not None:
|
||||
video_frame_list = [str(temp_path)] # Use current image as first frame
|
||||
# Add additional video frames if provided
|
||||
for frame in video_frames[1:]:
|
||||
frame_path = files_for_qwen2vl / f"temp_frame_{len(video_frame_list)}.png"
|
||||
ToPILImage()(frame.permute(2, 0, 1)).save(frame_path)
|
||||
video_frame_list.append(str(frame_path))
|
||||
|
||||
def generate(
|
||||
self,
|
||||
text_input,
|
||||
model_name,
|
||||
memory_mode="ComfyUI managed (BF16)",
|
||||
max_new_tokens=512,
|
||||
temperature=0.2,
|
||||
top_p=0.9,
|
||||
image=None,
|
||||
video_frames=None,
|
||||
fps=1.0,
|
||||
attention_mode="Auto (SDPA)",
|
||||
min_pixels=256 * 28 * 28,
|
||||
max_pixels=1280 * 28 * 28,
|
||||
unload_after=False,
|
||||
):
|
||||
if min_pixels > max_pixels:
|
||||
raise ValueError("min_pixels cannot be greater than max_pixels.")
|
||||
if image is None and video_frames is None:
|
||||
raise ValueError("Connect either image or video_frames.")
|
||||
key = (
|
||||
model_name,
|
||||
memory_mode,
|
||||
attention_mode,
|
||||
int(min_pixels),
|
||||
int(max_pixels),
|
||||
)
|
||||
predictor = self.get_or_create_model(
|
||||
key,
|
||||
lambda: Qwen2VLPredictor(
|
||||
model_name,
|
||||
memory_mode,
|
||||
attention_mode,
|
||||
min_pixels,
|
||||
max_pixels,
|
||||
),
|
||||
)
|
||||
try:
|
||||
# Generate response
|
||||
response = self.predictor.generate_predictions(
|
||||
temp_path,
|
||||
text_input,
|
||||
max_new_tokens=max_new_tokens,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
video_frames=video_frame_list,
|
||||
fps=fps
|
||||
)
|
||||
|
||||
# Clean up all temporary files
|
||||
try:
|
||||
os.remove(temp_path)
|
||||
if video_frame_list:
|
||||
for frame_path in video_frame_list[1:]:
|
||||
try:
|
||||
os.remove(frame_path)
|
||||
except:
|
||||
pass
|
||||
except:
|
||||
pass
|
||||
|
||||
return (response,)
|
||||
|
||||
except Exception as e:
|
||||
return (f"Error during generation: {str(e)}",)
|
||||
if video_frames is None:
|
||||
result = predictor.generate_images(
|
||||
image,
|
||||
text_input,
|
||||
max_new_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
)
|
||||
else:
|
||||
result = predictor.generate_video(
|
||||
image,
|
||||
video_frames,
|
||||
text_input,
|
||||
max_new_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
fps,
|
||||
)
|
||||
return (result,)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
# Register the node
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"Qwen2VLNode": Qwen2VLNode
|
||||
}
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"Qwen2VLNode": "Qwen2-VL Model"
|
||||
}
|
||||
NODE_CLASS_MAPPINGS = {"Qwen2VLNode": Qwen2VLNode}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Qwen2VLNode": "Qwen2-VL"}
|
||||
|
||||
@@ -0,0 +1,751 @@
|
||||
"""Shared runtime helpers for ComfyUI VLM nodes.
|
||||
|
||||
The important design rule in this module is that importing a node must never
|
||||
download a model, install a package, or allocate VRAM. Models are created on
|
||||
first execution and, where possible, registered with ComfyUI's own model
|
||||
manager so they participate in smart VRAM offloading.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import base64
|
||||
import gc
|
||||
import importlib
|
||||
import inspect
|
||||
import io
|
||||
import logging
|
||||
import os
|
||||
import platform
|
||||
import threading
|
||||
from contextlib import nullcontext
|
||||
from dataclasses import dataclass
|
||||
from importlib import metadata
|
||||
from pathlib import Path
|
||||
from typing import Any, Callable, Iterable, Mapping
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import Image
|
||||
|
||||
import folder_paths
|
||||
|
||||
LOGGER = logging.getLogger("ComfyUI_VLM_nodes")
|
||||
GGUF_EXTENSIONS = {".gguf"}
|
||||
|
||||
|
||||
class OptionalDependencyError(RuntimeError):
|
||||
"""Raised only when a node that needs an optional package is executed."""
|
||||
|
||||
|
||||
def require_module(import_name: str, package_name: str | None = None):
|
||||
"""Import an optional dependency with an actionable, non-destructive error."""
|
||||
|
||||
try:
|
||||
return importlib.import_module(import_name)
|
||||
except Exception as exc:
|
||||
package = package_name or import_name.split(".", 1)[0]
|
||||
raise OptionalDependencyError(
|
||||
f"This node requires the optional package '{package}'. "
|
||||
f"Install it into ComfyUI's Python environment, then restart ComfyUI. "
|
||||
"The node pack intentionally does not run pip or compile packages at startup."
|
||||
) from exc
|
||||
|
||||
|
||||
def register_model_folder() -> Path:
|
||||
"""Register the shared GGUF/model directory once and return its first path."""
|
||||
|
||||
model_dir = Path(folder_paths.models_dir) / "LLavacheckpoints"
|
||||
model_dir.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
existing = folder_paths.folder_names_and_paths.get("LLavacheckpoints")
|
||||
if existing:
|
||||
paths, extensions = existing
|
||||
normalized_paths = [str(Path(path)) for path in paths]
|
||||
if str(model_dir) not in normalized_paths:
|
||||
normalized_paths.append(str(model_dir))
|
||||
folder_paths.folder_names_and_paths["LLavacheckpoints"] = (
|
||||
normalized_paths,
|
||||
set(extensions) | GGUF_EXTENSIONS,
|
||||
)
|
||||
else:
|
||||
folder_paths.folder_names_and_paths["LLavacheckpoints"] = (
|
||||
[str(model_dir)],
|
||||
GGUF_EXTENSIONS,
|
||||
)
|
||||
return model_dir
|
||||
|
||||
|
||||
def model_root() -> Path:
|
||||
paths = folder_paths.get_folder_paths("LLavacheckpoints")
|
||||
if not paths:
|
||||
return register_model_folder()
|
||||
root = Path(paths[0])
|
||||
root.mkdir(parents=True, exist_ok=True)
|
||||
return root
|
||||
|
||||
|
||||
def model_cache_dir(name: str) -> Path:
|
||||
path = model_root() / name
|
||||
path.mkdir(parents=True, exist_ok=True)
|
||||
return path
|
||||
|
||||
|
||||
def resolve_model_path(filename: str) -> Path:
|
||||
getter = getattr(folder_paths, "get_full_path_or_raise", None)
|
||||
if getter is not None:
|
||||
return Path(getter("LLavacheckpoints", filename))
|
||||
path = folder_paths.get_full_path("LLavacheckpoints", filename)
|
||||
if path is None:
|
||||
raise FileNotFoundError(
|
||||
f"Model '{filename}' was not found in {model_root()}."
|
||||
)
|
||||
return Path(path)
|
||||
|
||||
|
||||
def normalize_hf_model_id(value: str) -> str:
|
||||
model_id = (value or "").strip().rstrip("/")
|
||||
for prefix in ("https://huggingface.co/", "http://huggingface.co/"):
|
||||
if model_id.startswith(prefix):
|
||||
model_id = model_id[len(prefix) :]
|
||||
break
|
||||
if not model_id or "/" not in model_id:
|
||||
raise ValueError(
|
||||
"Enter a Hugging Face repository as 'owner/model' or a full "
|
||||
"https://huggingface.co/owner/model URL."
|
||||
)
|
||||
return model_id
|
||||
|
||||
|
||||
def snapshot_download(repo_id: str, subdirectory: str, **kwargs: Any) -> Path:
|
||||
hub = require_module("huggingface_hub", "huggingface-hub")
|
||||
destination = model_cache_dir(subdirectory)
|
||||
download_kwargs = {
|
||||
"repo_id": repo_id,
|
||||
"local_dir": str(destination),
|
||||
"local_files_only": False,
|
||||
}
|
||||
download_kwargs.update(kwargs)
|
||||
# local_dir_use_symlinks was removed from newer huggingface-hub versions.
|
||||
if "local_dir_use_symlinks" in inspect.signature(
|
||||
hub.snapshot_download
|
||||
).parameters:
|
||||
download_kwargs.setdefault("local_dir_use_symlinks", False)
|
||||
return Path(hub.snapshot_download(**download_kwargs))
|
||||
|
||||
|
||||
def hf_download(
|
||||
repo_id: str, filename: str, subdirectory: str, **kwargs: Any
|
||||
) -> Path:
|
||||
hub = require_module("huggingface_hub", "huggingface-hub")
|
||||
destination = model_cache_dir(subdirectory)
|
||||
download_kwargs = {
|
||||
"repo_id": repo_id,
|
||||
"filename": filename,
|
||||
"local_dir": str(destination),
|
||||
}
|
||||
download_kwargs.update(kwargs)
|
||||
if "local_dir_use_symlinks" in inspect.signature(
|
||||
hub.hf_hub_download
|
||||
).parameters:
|
||||
download_kwargs.setdefault("local_dir_use_symlinks", False)
|
||||
return Path(hub.hf_hub_download(**download_kwargs))
|
||||
|
||||
|
||||
def tensor_to_pil(image: torch.Tensor, index: int = 0) -> Image.Image:
|
||||
"""Convert a Comfy IMAGE tensor to an RGB PIL image without torchvision."""
|
||||
|
||||
if not isinstance(image, torch.Tensor):
|
||||
raise TypeError(f"Expected a torch.Tensor, got {type(image).__name__}.")
|
||||
value = image.detach()
|
||||
if value.ndim == 4:
|
||||
if not 0 <= index < value.shape[0]:
|
||||
raise IndexError(f"Image batch index {index} is out of range.")
|
||||
value = value[index]
|
||||
if value.ndim == 2:
|
||||
value = value.unsqueeze(-1)
|
||||
if value.ndim != 3:
|
||||
raise ValueError(
|
||||
f"Expected an HWC/BHWC or CHW/BCHW image tensor, got {tuple(value.shape)}."
|
||||
)
|
||||
|
||||
# ComfyUI uses HWC. CHW is accepted for compatibility with older callers.
|
||||
if value.shape[-1] not in (1, 3, 4) and value.shape[0] in (1, 3, 4):
|
||||
value = value.permute(1, 2, 0)
|
||||
if value.shape[-1] not in (1, 3, 4):
|
||||
raise ValueError(f"Unsupported image channel shape: {tuple(value.shape)}.")
|
||||
|
||||
value = torch.nan_to_num(
|
||||
value.to(device="cpu", dtype=torch.float32), nan=0.0, posinf=1.0, neginf=0.0
|
||||
)
|
||||
if value.numel() and (value.max() > 1.0 or value.min() < 0.0):
|
||||
value = value / 255.0
|
||||
array = (
|
||||
value.clamp(0.0, 1.0).mul(255.0).round().to(torch.uint8).numpy()
|
||||
)
|
||||
if array.shape[-1] == 1:
|
||||
array = np.repeat(array, 3, axis=-1)
|
||||
elif array.shape[-1] == 4:
|
||||
array = array[..., :3]
|
||||
return Image.fromarray(array, mode="RGB")
|
||||
|
||||
|
||||
def tensor_batch_to_pil(images: torch.Tensor) -> list[Image.Image]:
|
||||
if images.ndim == 3:
|
||||
return [tensor_to_pil(images)]
|
||||
if images.ndim != 4:
|
||||
raise ValueError(f"Expected an IMAGE batch, got {tuple(images.shape)}.")
|
||||
return [tensor_to_pil(images, index) for index in range(images.shape[0])]
|
||||
|
||||
|
||||
def pil_to_tensor(image: Image.Image) -> torch.Tensor:
|
||||
array = np.asarray(image.convert("RGB"), dtype=np.float32) / 255.0
|
||||
return torch.from_numpy(array.copy()).unsqueeze(0)
|
||||
|
||||
|
||||
def pil_mask_to_tensor(image: Image.Image) -> torch.Tensor:
|
||||
array = np.asarray(image.convert("L"), dtype=np.float32) / 255.0
|
||||
return torch.from_numpy(array.copy()).unsqueeze(0)
|
||||
|
||||
|
||||
def image_data_uri(image: Image.Image) -> str:
|
||||
buffer = io.BytesIO()
|
||||
image.save(buffer, format="PNG", optimize=True)
|
||||
encoded = base64.b64encode(buffer.getvalue()).decode("ascii")
|
||||
return f"data:image/png;base64,{encoded}"
|
||||
|
||||
|
||||
def batch_text(responses: Iterable[str]) -> str:
|
||||
items = [str(item).strip() for item in responses]
|
||||
if len(items) <= 1:
|
||||
return items[0] if items else ""
|
||||
return "\n\n".join(
|
||||
f"--- Image {index} ---\n{text}" for index, text in enumerate(items, 1)
|
||||
)
|
||||
|
||||
|
||||
def execution_device() -> torch.device:
|
||||
"""Return ComfyUI's selected device, with portable standalone fallbacks."""
|
||||
|
||||
try:
|
||||
import comfy.model_management as model_management
|
||||
|
||||
return model_management.get_torch_device()
|
||||
except Exception:
|
||||
if torch.cuda.is_available():
|
||||
# PyTorch intentionally exposes both NVIDIA CUDA and AMD ROCm
|
||||
# devices through torch.cuda.
|
||||
return torch.device("cuda", torch.cuda.current_device())
|
||||
xpu = getattr(torch, "xpu", None)
|
||||
if xpu is not None:
|
||||
try:
|
||||
if xpu.is_available():
|
||||
return torch.device("xpu", xpu.current_device())
|
||||
except Exception:
|
||||
pass
|
||||
mps = getattr(getattr(torch, "backends", None), "mps", None)
|
||||
if mps is not None:
|
||||
try:
|
||||
if mps.is_available():
|
||||
return torch.device("mps")
|
||||
except Exception:
|
||||
pass
|
||||
return torch.device("cpu")
|
||||
|
||||
|
||||
def accelerator_backend(device: torch.device | None = None) -> str:
|
||||
"""Return a stable, user-facing name for the active PyTorch backend."""
|
||||
|
||||
device = device or execution_device()
|
||||
if device.type == "cuda":
|
||||
return (
|
||||
"amd-rocm"
|
||||
if getattr(getattr(torch, "version", None), "hip", None)
|
||||
else "nvidia-cuda"
|
||||
)
|
||||
return {
|
||||
"mps": "apple-metal",
|
||||
"xpu": "intel-xpu",
|
||||
"cpu": "cpu",
|
||||
"privateuseone": "directml-or-privateuse1",
|
||||
"npu": "ascend-npu",
|
||||
"mlu": "cambricon-mlu",
|
||||
}.get(device.type, device.type)
|
||||
|
||||
|
||||
def supports_bfloat16(device: torch.device | None = None) -> bool:
|
||||
"""Feature-detect BF16 without initializing an unavailable accelerator."""
|
||||
|
||||
device = device or execution_device()
|
||||
if device.type == "cuda":
|
||||
checker = getattr(torch.cuda, "is_bf16_supported", None)
|
||||
try:
|
||||
return bool(checker()) if checker is not None else False
|
||||
except Exception:
|
||||
return False
|
||||
if device.type == "xpu":
|
||||
checker = getattr(getattr(torch, "xpu", None), "is_bf16_supported", None)
|
||||
try:
|
||||
return bool(checker()) if checker is not None else False
|
||||
except Exception:
|
||||
return False
|
||||
if device.type == "mps":
|
||||
# MPS BF16 requires macOS 14+. Older PyTorch releases may not expose
|
||||
# the version probe, in which case FP16 is the safe portable choice.
|
||||
checker = getattr(
|
||||
getattr(getattr(torch, "backends", None), "mps", None),
|
||||
"is_macos_or_newer",
|
||||
None,
|
||||
)
|
||||
try:
|
||||
return bool(checker(14, 0)) if checker is not None else False
|
||||
except Exception:
|
||||
return False
|
||||
return False
|
||||
|
||||
|
||||
def torch_dtype(
|
||||
name: str | None = None,
|
||||
device: torch.device | None = None,
|
||||
) -> torch.dtype:
|
||||
"""Choose a dtype that the selected ComfyUI backend can execute safely."""
|
||||
|
||||
device = device or execution_device()
|
||||
requested = (name or "auto").lower()
|
||||
if requested in {"float32", "fp32"}:
|
||||
return torch.float32
|
||||
if requested in {"float16", "fp16"}:
|
||||
return (
|
||||
torch.float16
|
||||
if device.type in {"cuda", "mps", "xpu"}
|
||||
else torch.float32
|
||||
)
|
||||
if requested in {"bfloat16", "bf16"}:
|
||||
if supports_bfloat16(device):
|
||||
return torch.bfloat16
|
||||
return (
|
||||
torch.float16
|
||||
if device.type in {"cuda", "mps", "xpu"}
|
||||
else torch.float32
|
||||
)
|
||||
if supports_bfloat16(device):
|
||||
return torch.bfloat16
|
||||
return (
|
||||
torch.float16
|
||||
if device.type in {"cuda", "mps", "xpu"}
|
||||
else torch.float32
|
||||
)
|
||||
|
||||
|
||||
def _release_tuple(distribution: str) -> tuple[int, ...]:
|
||||
try:
|
||||
value = metadata.version(distribution)
|
||||
except metadata.PackageNotFoundError:
|
||||
return ()
|
||||
parts = []
|
||||
for part in value.split("."):
|
||||
digits = "".join(character for character in part if character.isdigit())
|
||||
if not digits:
|
||||
break
|
||||
parts.append(int(digits))
|
||||
return tuple(parts)
|
||||
|
||||
|
||||
def require_quantization_backend(feature: str) -> torch.device:
|
||||
"""Validate the maintained bitsandbytes backend for the selected device."""
|
||||
|
||||
device = execution_device()
|
||||
backend = accelerator_backend(device)
|
||||
supported = {"nvidia-cuda", "amd-rocm", "intel-xpu", "apple-metal", "cpu"}
|
||||
if backend not in supported:
|
||||
raise RuntimeError(
|
||||
f"{feature} is not supported on the active {backend} backend. "
|
||||
"Use ComfyUI managed precision or CPU mode."
|
||||
)
|
||||
if (
|
||||
platform.system() == "Darwin"
|
||||
and platform.machine().lower() not in {"arm64", "aarch64"}
|
||||
):
|
||||
raise RuntimeError(
|
||||
f"{feature} needs bitsandbytes, which has no official Intel-macOS "
|
||||
"wheel. Use ComfyUI managed precision, or use an Apple Silicon Mac."
|
||||
)
|
||||
require_module("bitsandbytes")
|
||||
require_module("accelerate")
|
||||
if backend != "nvidia-cuda" and _release_tuple("bitsandbytes") < (0, 50):
|
||||
raise RuntimeError(
|
||||
f"{feature} on {backend} requires bitsandbytes 0.50 or newer. "
|
||||
"Upgrade requirements.txt in ComfyUI's Python environment."
|
||||
)
|
||||
return device
|
||||
|
||||
|
||||
def external_device_map(*, allow_auto_offload: bool = False):
|
||||
"""Create an Accelerate device map without assuming CUDA device zero."""
|
||||
|
||||
device = execution_device()
|
||||
if allow_auto_offload and device.type in {"cuda", "xpu"}:
|
||||
return "auto"
|
||||
return {"": str(device)}
|
||||
|
||||
|
||||
def runtime_diagnostics() -> dict[str, Any]:
|
||||
"""Return support information suitable for bug reports and CI logs."""
|
||||
|
||||
device = execution_device()
|
||||
packages = {}
|
||||
for distribution in (
|
||||
"accelerate",
|
||||
"bitsandbytes",
|
||||
"diffusers",
|
||||
"huggingface-hub",
|
||||
"llama-cpp-python",
|
||||
"qwen-vl-utils",
|
||||
"transformers",
|
||||
):
|
||||
try:
|
||||
packages[distribution] = metadata.version(distribution)
|
||||
except metadata.PackageNotFoundError:
|
||||
packages[distribution] = None
|
||||
return {
|
||||
"platform": platform.platform(),
|
||||
"machine": platform.machine(),
|
||||
"python": platform.python_version(),
|
||||
"torch": torch.__version__,
|
||||
"device": str(device),
|
||||
"backend": accelerator_backend(device),
|
||||
"bf16": supports_bfloat16(device),
|
||||
"torch_cuda": getattr(getattr(torch, "version", None), "cuda", None),
|
||||
"torch_hip": getattr(getattr(torch, "version", None), "hip", None),
|
||||
"packages": packages,
|
||||
}
|
||||
|
||||
|
||||
def model_device(model: torch.nn.Module) -> torch.device:
|
||||
try:
|
||||
return next(model.parameters()).device
|
||||
except StopIteration:
|
||||
return execution_device()
|
||||
|
||||
|
||||
def move_inputs(
|
||||
inputs: Mapping[str, Any],
|
||||
device: torch.device,
|
||||
*,
|
||||
floating_dtype: torch.dtype | None = None,
|
||||
) -> dict[str, Any]:
|
||||
moved: dict[str, Any] = {}
|
||||
for key, value in inputs.items():
|
||||
if not isinstance(value, torch.Tensor):
|
||||
moved[key] = value
|
||||
elif floating_dtype is not None and value.is_floating_point():
|
||||
moved[key] = value.to(device=device, dtype=floating_dtype)
|
||||
else:
|
||||
moved[key] = value.to(device=device)
|
||||
return moved
|
||||
|
||||
|
||||
class _ManagedModelAdapter(torch.nn.Module):
|
||||
"""Give arbitrary HF modules the mutable ``device`` ComfyUI expects.
|
||||
|
||||
Recent Transformers models expose ``device`` as a read-only property.
|
||||
ModelPatcher writes that attribute as residency changes, so wrapping the
|
||||
original module is necessary for current Qwen/Gemma and harmless for older
|
||||
torch modules. Attribute access remains transparent to node predictors.
|
||||
"""
|
||||
|
||||
def __init__(self, model: torch.nn.Module, device: torch.device):
|
||||
super().__init__()
|
||||
self.wrapped_model = model
|
||||
self.device = device
|
||||
|
||||
def forward(self, *args, **kwargs):
|
||||
return self.wrapped_model(*args, **kwargs)
|
||||
|
||||
def __getattr__(self, name):
|
||||
try:
|
||||
return super().__getattr__(name)
|
||||
except AttributeError:
|
||||
return getattr(self.wrapped_model, name)
|
||||
|
||||
|
||||
class ManagedTorchModel:
|
||||
"""Register an ordinary torch module with ComfyUI's smart VRAM manager."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
model: torch.nn.Module,
|
||||
*,
|
||||
processor: Any = None,
|
||||
load_device: torch.device | None = None,
|
||||
offload_device: torch.device | None = None,
|
||||
) -> None:
|
||||
import comfy.model_management as model_management
|
||||
from comfy.model_patcher import ModelPatcher
|
||||
|
||||
self.load_device = load_device or model_management.get_torch_device()
|
||||
self.offload_device = offload_device or (
|
||||
torch.device("cpu")
|
||||
if self.load_device.type != "cpu"
|
||||
else self.load_device
|
||||
)
|
||||
self.model = _ManagedModelAdapter(
|
||||
model.eval(), self.offload_device
|
||||
)
|
||||
self.processor = processor
|
||||
self.patcher = ModelPatcher(
|
||||
self.model,
|
||||
load_device=self.load_device,
|
||||
offload_device=self.offload_device,
|
||||
)
|
||||
self._lock = threading.RLock()
|
||||
self._closed = False
|
||||
|
||||
def ensure_loaded(self) -> torch.nn.Module:
|
||||
if self._closed:
|
||||
raise RuntimeError("This model handle has already been closed.")
|
||||
with self._lock:
|
||||
import comfy.model_management as model_management
|
||||
|
||||
model_management.load_models_gpu([self.patcher])
|
||||
return self.model
|
||||
|
||||
def unload(self) -> None:
|
||||
if self._closed:
|
||||
return
|
||||
with self._lock:
|
||||
import comfy.model_management as model_management
|
||||
|
||||
model_management.unload_model_and_clones(self.patcher)
|
||||
|
||||
def close(self) -> None:
|
||||
if self._closed:
|
||||
return
|
||||
self.unload()
|
||||
self._closed = True
|
||||
self.processor = None
|
||||
self.model = None
|
||||
self.patcher = None
|
||||
gc.collect()
|
||||
|
||||
|
||||
class CachedModelNode:
|
||||
"""Reusable node-instance cache that closes only the model it owns."""
|
||||
|
||||
def __init__(self) -> None:
|
||||
self._model_handle = None
|
||||
self._model_key = None
|
||||
|
||||
def get_or_create_model(self, key: Any, factory: Callable[[], Any]):
|
||||
if self._model_handle is None or self._model_key != key:
|
||||
close_handle(self._model_handle)
|
||||
self._model_handle = factory()
|
||||
self._model_key = key
|
||||
return self._model_handle
|
||||
|
||||
def clear_model(self) -> None:
|
||||
close_handle(self._model_handle)
|
||||
self._model_handle = None
|
||||
self._model_key = None
|
||||
|
||||
def maybe_clear_model(self, unload_after: bool) -> None:
|
||||
if unload_after:
|
||||
self.clear_model()
|
||||
|
||||
def __del__(self):
|
||||
try:
|
||||
self.clear_model()
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
|
||||
class ExternalTorchModel:
|
||||
"""Handle for models whose quantizer/device map cannot use ModelPatcher."""
|
||||
|
||||
def __init__(self, model: Any, *, processor: Any = None) -> None:
|
||||
self.model = model
|
||||
self.processor = processor
|
||||
self._closed = False
|
||||
|
||||
def ensure_loaded(self):
|
||||
if self._closed:
|
||||
raise RuntimeError("This model handle has already been closed.")
|
||||
return self.model
|
||||
|
||||
def unload(self) -> None:
|
||||
self.close()
|
||||
|
||||
def close(self) -> None:
|
||||
if self._closed:
|
||||
return
|
||||
self._closed = True
|
||||
model = self.model
|
||||
self.model = None
|
||||
self.processor = None
|
||||
if model is not None:
|
||||
close = getattr(model, "close", None)
|
||||
if callable(close):
|
||||
close()
|
||||
gc.collect()
|
||||
try:
|
||||
import comfy.model_management as model_management
|
||||
|
||||
model_management.soft_empty_cache()
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
|
||||
def reserve_external_vram(memory_required: int) -> None:
|
||||
"""Ask ComfyUI to make room before an external accelerator allocator."""
|
||||
|
||||
device = execution_device()
|
||||
if memory_required <= 0 or device.type == "cpu":
|
||||
return
|
||||
try:
|
||||
import comfy.model_management as model_management
|
||||
|
||||
model_management.free_memory(int(memory_required), device)
|
||||
except Exception as exc:
|
||||
LOGGER.debug("Could not reserve VRAM through ComfyUI: %s", exc)
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class LlavaClipConfig:
|
||||
model_path: Path
|
||||
|
||||
def create(self):
|
||||
module = require_module("llama_cpp.llama_chat_format", "llama-cpp-python")
|
||||
return module.Llava15ChatHandler(
|
||||
clip_model_path=str(self.model_path), verbose=False
|
||||
)
|
||||
|
||||
|
||||
class LlamaHandle:
|
||||
"""Lazy llama.cpp handle that owns and closes its exact GPU allocations."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
model_path: Path,
|
||||
*,
|
||||
n_ctx: int,
|
||||
n_gpu_layers: int,
|
||||
n_threads: int,
|
||||
chat_format: str | None = None,
|
||||
chat_handler_factory: Callable[[], Any] | None = None,
|
||||
seed: int = 42,
|
||||
) -> None:
|
||||
self.model_path = Path(model_path)
|
||||
self.n_ctx = int(n_ctx)
|
||||
self.n_gpu_layers = int(n_gpu_layers)
|
||||
self.n_threads = int(n_threads)
|
||||
self.chat_format = chat_format
|
||||
self.chat_handler_factory = chat_handler_factory
|
||||
self.seed = int(seed)
|
||||
self._llm = None
|
||||
self._chat_handler = None
|
||||
self._lock = threading.RLock()
|
||||
|
||||
@property
|
||||
def cache_key(self) -> tuple[Any, ...]:
|
||||
return (
|
||||
str(self.model_path),
|
||||
self.n_ctx,
|
||||
self.n_gpu_layers,
|
||||
self.n_threads,
|
||||
self.chat_format,
|
||||
)
|
||||
|
||||
def ensure_loaded(self):
|
||||
if self._llm is not None:
|
||||
return self._llm
|
||||
with self._lock:
|
||||
if self._llm is not None:
|
||||
return self._llm
|
||||
if not self.model_path.is_file():
|
||||
raise FileNotFoundError(f"GGUF model not found: {self.model_path}")
|
||||
|
||||
# llama.cpp owns its accelerator allocator, so reserve enough room
|
||||
# through ComfyUI instead of emptying a global backend cache.
|
||||
if self.n_gpu_layers != 0:
|
||||
reserve_external_vram(self.model_path.stat().st_size)
|
||||
|
||||
llama_cpp = require_module("llama_cpp", "llama-cpp-python")
|
||||
if self.chat_handler_factory is not None:
|
||||
self._chat_handler = self.chat_handler_factory()
|
||||
|
||||
requested = {
|
||||
"model_path": str(self.model_path),
|
||||
"chat_handler": self._chat_handler,
|
||||
"chat_format": self.chat_format,
|
||||
"n_ctx": self.n_ctx,
|
||||
"n_gpu_layers": self.n_gpu_layers,
|
||||
"n_threads": self.n_threads,
|
||||
"n_batch": min(1024, self.n_ctx),
|
||||
"offload_kqv": self.n_gpu_layers != 0,
|
||||
"flash_attn": self.n_gpu_layers != 0,
|
||||
"use_mlock": False,
|
||||
"embedding": False,
|
||||
"verbose": False,
|
||||
"seed": self.seed,
|
||||
}
|
||||
signature = inspect.signature(llama_cpp.Llama.__init__)
|
||||
kwargs = {
|
||||
key: value
|
||||
for key, value in requested.items()
|
||||
if key in signature.parameters and value is not None
|
||||
}
|
||||
self._llm = llama_cpp.Llama(**kwargs)
|
||||
return self._llm
|
||||
|
||||
def close(self) -> None:
|
||||
with self._lock:
|
||||
llm, handler = self._llm, self._chat_handler
|
||||
self._llm = None
|
||||
self._chat_handler = None
|
||||
if llm is not None:
|
||||
close = getattr(llm, "close", None)
|
||||
if callable(close):
|
||||
close()
|
||||
if handler is not None:
|
||||
close = getattr(handler, "close", None)
|
||||
if callable(close):
|
||||
close()
|
||||
gc.collect()
|
||||
try:
|
||||
import comfy.model_management as model_management
|
||||
|
||||
model_management.soft_empty_cache()
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
def __getattr__(self, name: str):
|
||||
if name.startswith("_"):
|
||||
raise AttributeError(name)
|
||||
return getattr(self.ensure_loaded(), name)
|
||||
|
||||
def __del__(self):
|
||||
try:
|
||||
self.close()
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
|
||||
def unwrap_llm(model: Any):
|
||||
ensure_loaded = getattr(model, "ensure_loaded", None)
|
||||
return ensure_loaded() if callable(ensure_loaded) else model
|
||||
|
||||
|
||||
def close_handle(handle: Any) -> None:
|
||||
if handle is None:
|
||||
return
|
||||
close = getattr(handle, "close", None)
|
||||
if callable(close):
|
||||
close()
|
||||
|
||||
|
||||
def inference_context(device: torch.device, dtype: torch.dtype):
|
||||
if (
|
||||
device.type in {"cuda", "xpu"}
|
||||
and dtype in {torch.float16, torch.bfloat16}
|
||||
):
|
||||
return torch.autocast(device.type, dtype=dtype)
|
||||
return nullcontext()
|
||||
+4
-4
@@ -35,7 +35,7 @@ class JsonToText:
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"text": ("STRING", {"forceInput": True}),
|
||||
"text": ("STRING",),
|
||||
}
|
||||
}
|
||||
|
||||
@@ -66,7 +66,7 @@ class JsonToText:
|
||||
merged_ideas.append(f"{key}: {value}")
|
||||
|
||||
formatted_output_str = "\n\n".join(merged_ideas)
|
||||
return {"ui": {"text": formatted_output_str}, "result": (formatted_output_str,)}
|
||||
return {"ui": {"text": [formatted_output_str]}, "result": (formatted_output_str,)}
|
||||
|
||||
class ViewText:
|
||||
def __init__(self):
|
||||
@@ -76,7 +76,7 @@ class ViewText:
|
||||
def INPUT_TYPES(s):
|
||||
return {
|
||||
"required": {
|
||||
"text": ("STRING", {"forceInput": True}),
|
||||
"text": ("STRING",),
|
||||
}
|
||||
}
|
||||
|
||||
@@ -88,7 +88,7 @@ class ViewText:
|
||||
|
||||
def view_text(self, text):
|
||||
# Parse the combined JSON string
|
||||
return {"ui": {"text": text}, "result": (text,)}
|
||||
return {"ui": {"text": [text]}, "result": (text,)}
|
||||
|
||||
# A dictionary that contains all nodes you want to export with their names
|
||||
NODE_CLASS_MAPPINGS = {"SimpleText": SimpleText,
|
||||
|
||||
+1005
-599
File diff suppressed because it is too large
Load Diff
+92
-82
@@ -1,84 +1,86 @@
|
||||
from pathlib import Path
|
||||
from transformers import AutoModel, AutoProcessor, StoppingCriteria, StoppingCriteriaList
|
||||
"""UForm Gen2 Qwen node with safe lazy loading."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import torch
|
||||
from PIL import Image
|
||||
from torchvision.transforms import ToPILImage
|
||||
from huggingface_hub import snapshot_download
|
||||
import folder_paths
|
||||
# Define the directory for saving files related to uform-gen2-qwen
|
||||
files_for_uform_gen2_qwen = Path(folder_paths.folder_names_and_paths["LLavacheckpoints"][0][0]) / "files_for_uform_gen2_qwen"
|
||||
files_for_uform_gen2_qwen.mkdir(parents=True, exist_ok=True) # Ensure the directory exists
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
inference_context,
|
||||
model_device,
|
||||
require_module,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
MODEL_ID = "unum-cloud/uform-gen2-qwen-500m"
|
||||
|
||||
class StopOnTokens(StoppingCriteria):
|
||||
def __call__(self, input_ids: torch.LongTensor, scores: torch.FloatTensor, **kwargs) -> bool:
|
||||
stop_ids = [151645] # Define stop tokens as per your model's specifics
|
||||
for stop_id in stop_ids:
|
||||
if input_ids[0][-1] == stop_id:
|
||||
return True
|
||||
return False
|
||||
|
||||
class UformGen2QwenChat:
|
||||
def __init__(self):
|
||||
self.model_path = snapshot_download("unum-cloud/uform-gen2-qwen-500m",
|
||||
local_dir=files_for_uform_gen2_qwen,
|
||||
force_download=False, # Set to True if you always want to download, regardless of local copy
|
||||
local_files_only=False, # Set to False to allow downloading if not available locally
|
||||
local_dir_use_symlinks="auto") # or set to True/False based on your symlink preference
|
||||
self.device = "cuda:0" if torch.cuda.is_available() else "cpu"
|
||||
self.model = AutoModel.from_pretrained(self.model_path, trust_remote_code=True).to(self.device)
|
||||
self.processor = AutoProcessor.from_pretrained(self.model_path, trust_remote_code=True)
|
||||
|
||||
def chat_response(self, message, history, image_path):
|
||||
stop = StopOnTokens()
|
||||
messages = [{"role": "system", "content": "You are a helpful Assistant."}]
|
||||
|
||||
for user_msg, assistant_msg in history:
|
||||
messages.append({"role": "user", "content": user_msg})
|
||||
messages.append({"role": "assistant", "content": assistant_msg})
|
||||
|
||||
if len(messages) == 1:
|
||||
message = f" <image>{message}"
|
||||
|
||||
messages.append({"role": "user", "content": message})
|
||||
|
||||
model_inputs = self.processor.tokenizer.apply_chat_template(
|
||||
messages,
|
||||
add_generation_prompt=True,
|
||||
return_tensors="pt"
|
||||
transformers = require_module("transformers")
|
||||
model_path = snapshot_download(
|
||||
MODEL_ID, "uform-gen2-qwen", ignore_patterns=["*.bin"]
|
||||
)
|
||||
|
||||
image = Image.open(image_path) # Load image using PIL
|
||||
image_tensor = (
|
||||
self.processor.feature_extractor(image)
|
||||
.unsqueeze(0)
|
||||
self.dtype = torch_dtype("float16")
|
||||
model = transformers.AutoModel.from_pretrained(
|
||||
model_path,
|
||||
trust_remote_code=True,
|
||||
torch_dtype=self.dtype,
|
||||
).eval()
|
||||
self.processor = transformers.AutoProcessor.from_pretrained(
|
||||
model_path, trust_remote_code=True
|
||||
)
|
||||
self.handle = ManagedTorchModel(model, processor=self.processor)
|
||||
|
||||
attention_mask = torch.ones(
|
||||
1, model_inputs.shape[1] + self.processor.num_image_latents - 1
|
||||
)
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
model_inputs = {
|
||||
"input_ids": model_inputs,
|
||||
"images": image_tensor,
|
||||
"attention_mask": attention_mask
|
||||
}
|
||||
def chat(self, images, question, max_new_tokens):
|
||||
results = []
|
||||
for image in tensor_batch_to_pil(images):
|
||||
messages = [
|
||||
{"role": "system", "content": "You are a helpful assistant."},
|
||||
{"role": "user", "content": f"<image>{question}"},
|
||||
]
|
||||
input_ids = self.processor.tokenizer.apply_chat_template(
|
||||
messages,
|
||||
add_generation_prompt=True,
|
||||
return_tensors="pt",
|
||||
)
|
||||
image_tensor = self.processor.feature_extractor(image).unsqueeze(0)
|
||||
attention_mask = torch.ones(
|
||||
1,
|
||||
input_ids.shape[1] + self.processor.num_image_latents - 1,
|
||||
dtype=torch.long,
|
||||
)
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
model_inputs = {
|
||||
"input_ids": input_ids.to(device),
|
||||
"images": image_tensor.to(device),
|
||||
"attention_mask": attention_mask.to(device),
|
||||
}
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
output = model.generate(
|
||||
**model_inputs,
|
||||
max_new_tokens=int(max_new_tokens),
|
||||
eos_token_id=self.processor.tokenizer.eos_token_id,
|
||||
)
|
||||
generated = output[0, input_ids.shape[-1] :]
|
||||
results.append(
|
||||
self.processor.tokenizer.decode(
|
||||
generated, skip_special_tokens=True
|
||||
).strip()
|
||||
)
|
||||
return batch_text(results)
|
||||
|
||||
model_inputs = {k: v.to(self.device) for k, v in model_inputs.items()}
|
||||
|
||||
output = self.model.generate(
|
||||
**model_inputs,
|
||||
max_new_tokens=1024,
|
||||
stopping_criteria=StoppingCriteriaList([stop])
|
||||
)
|
||||
|
||||
response_text = self.processor.tokenizer.decode(output[0], skip_special_tokens=True)
|
||||
return response_text
|
||||
|
||||
# Example of integrating UformGen2QwenChat into a node-like structure
|
||||
class UformGen2QwenNode:
|
||||
def __init__(self):
|
||||
self.chat_model = UformGen2QwenChat()
|
||||
|
||||
class UformGen2QwenNode(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
@@ -88,26 +90,34 @@ class UformGen2QwenNode:
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "",
|
||||
"default": "Describe this image in detail.",
|
||||
},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 512, "min": 1, "max": 4096},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
|
||||
FUNCTION = "uform_gen2_qwen_chat"
|
||||
|
||||
CATEGORY = "VLM Nodes/UformGen2Qwen"
|
||||
|
||||
def uform_gen2_qwen_chat(self, image, question):
|
||||
history = [] # Example empty history
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
temp_path = files_for_uform_gen2_qwen / "temp.png"
|
||||
pil_image.save(temp_path)
|
||||
|
||||
response = self.chat_model.chat_response(question, history, temp_path)
|
||||
return (response.split("assistant\n", 1)[1], )
|
||||
def uform_gen2_qwen_chat(
|
||||
self, image, question, max_new_tokens=512, unload_after=False
|
||||
):
|
||||
predictor = self.get_or_create_model(
|
||||
MODEL_ID, UformGen2QwenChat
|
||||
)
|
||||
try:
|
||||
return (predictor.chat(image, question, max_new_tokens),)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"UformGen2QwenNode": UformGen2QwenNode}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"UformGen2QwenNode": "UformGen2 Qwen Node"}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"UformGen2QwenNode": "UForm Gen2 Qwen"}
|
||||
|
||||
+42
-5
@@ -1,15 +1,52 @@
|
||||
[project]
|
||||
name = "comfyui_vlm_nodes"
|
||||
description = "Custom Nodes for Vision Language Models (VLM) , Large Language Models (LLM), Image Captioning, Automatic Prompt Generation, Creative and Consistent Prompt Suggestion, Keyword Extraction"
|
||||
version = "1.0.6"
|
||||
version = "2.1.0"
|
||||
description = "Production-ready local and API vision-language nodes for ComfyUI"
|
||||
readme = "README.md"
|
||||
requires-python = ">=3.10"
|
||||
license = { file = "LICENSE" }
|
||||
dependencies = ["accelerate>=0.27.0", "bitsandbytes", "cffi", "decord" , "diffusers" , "diskcache" , "einops>=0.7.0" , "gitpython", "huggingface-hub>=0.20.3", "moviepy", "openai>=0.27.8", "opencv-python", "optimum>=1.17.0", "pillow>=9.4.0", "py-cpuinfo>=3.3.0", "python-dateutil>=2.7.0", "pytz", "qwen-vl-utils", "safetensors>=0.4.1", "scikit-build", "six", "soundfile", "symusic", "torch>=2.0.1,<3.0.0", "torchvision>=0.15.2", "transformers>=4.38.2", "typing"]
|
||||
dependencies = [
|
||||
"accelerate>=1.1,<2",
|
||||
"bitsandbytes>=0.50,<1; (sys_platform == 'linux' and platform_machine == 'x86_64') or (sys_platform == 'linux' and platform_machine == 'aarch64') or (sys_platform == 'win32' and platform_machine == 'AMD64') or (sys_platform == 'win32' and platform_machine == 'ARM64') or (sys_platform == 'darwin' and platform_machine == 'arm64')",
|
||||
"diffusers>=0.34,<1",
|
||||
"einops>=0.8,<1",
|
||||
"huggingface-hub>=1.5,<2",
|
||||
"openai>=1.30,<3",
|
||||
"pydantic>=2.7,<3",
|
||||
"qwen-vl-utils>=0.0.14",
|
||||
"safetensors>=0.4.3",
|
||||
"soundfile>=0.12",
|
||||
"symusic>=0.5",
|
||||
"transformers>=5.4,<6",
|
||||
]
|
||||
classifiers = [
|
||||
"Operating System :: Microsoft :: Windows",
|
||||
"Operating System :: POSIX :: Linux",
|
||||
"Operating System :: MacOS",
|
||||
"Environment :: GPU :: NVIDIA CUDA",
|
||||
"Environment :: GPU :: AMD ROCm",
|
||||
"Environment :: GPU :: Intel Arc",
|
||||
"Environment :: GPU :: Apple Metal",
|
||||
"Programming Language :: Python :: 3.10",
|
||||
"Programming Language :: Python :: 3.11",
|
||||
"Programming Language :: Python :: 3.12",
|
||||
"Programming Language :: Python :: 3.13",
|
||||
]
|
||||
|
||||
[project.optional-dependencies]
|
||||
quantization = [
|
||||
"accelerate>=1.1,<2",
|
||||
"bitsandbytes>=0.50,<1",
|
||||
]
|
||||
gguf = [
|
||||
"llama-cpp-python>=0.3.15",
|
||||
]
|
||||
|
||||
[project.urls]
|
||||
Repository = "https://github.com/gokayfem/ComfyUI_VLM_nodes"
|
||||
Issues = "https://github.com/gokayfem/ComfyUI_VLM_nodes/issues"
|
||||
|
||||
[tool.comfy]
|
||||
PublisherId = "gokayfem"
|
||||
DisplayName = "ComfyUI_VLM_nodes"
|
||||
DisplayName = "ComfyUI VLM Nodes"
|
||||
Icon = ""
|
||||
Models = [{location = "/checkpoints/model.safetensor", model_url = "https://example.com/model.zip"}]
|
||||
|
||||
@@ -0,0 +1,4 @@
|
||||
# Optional GGUF backend. This default may build the CPU backend from source.
|
||||
# Prefer the official CUDA, Metal, ROCm/HIP, Vulkan, or SYCL wheel/build from:
|
||||
# https://github.com/abetlen/llama-cpp-python
|
||||
llama-cpp-python>=0.3.15
|
||||
@@ -0,0 +1,5 @@
|
||||
# Optional maintained 4-bit/8-bit backend.
|
||||
# Official 0.50+ wheels cover NVIDIA CUDA, AMD ROCm, Intel XPU/CPU,
|
||||
# Apple Silicon, and supported Windows/Linux CPU architectures.
|
||||
accelerate>=1.1,<2
|
||||
bitsandbytes>=0.50,<1
|
||||
+16
-29
@@ -1,29 +1,16 @@
|
||||
accelerate>=0.32.1
|
||||
bitsandbytes
|
||||
cffi
|
||||
decord
|
||||
diffusers >=0.31.0
|
||||
diskcache
|
||||
einops>=0.7.0
|
||||
gitpython
|
||||
huggingface-hub>=0.26.2
|
||||
matplotlib
|
||||
moviepy
|
||||
numpy>=1.22.4,<2.0.0
|
||||
openai>=0.27.8
|
||||
opencv-python
|
||||
optimum>=1.17.0
|
||||
pillow>=9.4.0
|
||||
py-cpuinfo>=3.3.0
|
||||
python-dateutil>=2.7.0
|
||||
pytz
|
||||
qwen-vl-utils
|
||||
safetensors>=0.4.1
|
||||
scikit-build
|
||||
six
|
||||
soundfile
|
||||
symusic
|
||||
torch>=2.0.1
|
||||
torchvision>=0.15.2
|
||||
transformers>=4.46
|
||||
typing
|
||||
# ComfyUI provides torch, torchvision, numpy and Pillow.
|
||||
# Keep this list resolver-friendly; no package is installed during node import.
|
||||
accelerate>=1.1,<2
|
||||
# Official wheels: Linux x86_64/aarch64, Windows AMD64/ARM64, macOS arm64.
|
||||
# Unsupported machines keep every non-quantized node instead of failing install.
|
||||
bitsandbytes>=0.50,<1; (sys_platform == "linux" and platform_machine == "x86_64") or (sys_platform == "linux" and platform_machine == "aarch64") or (sys_platform == "win32" and platform_machine == "AMD64") or (sys_platform == "win32" and platform_machine == "ARM64") or (sys_platform == "darwin" and platform_machine == "arm64")
|
||||
diffusers>=0.34,<1
|
||||
einops>=0.8,<1
|
||||
huggingface-hub>=1.5,<2
|
||||
openai>=1.30,<3
|
||||
pydantic>=2.7,<3
|
||||
qwen-vl-utils>=0.0.14
|
||||
safetensors>=0.4.3
|
||||
soundfile>=0.12
|
||||
symusic>=0.5
|
||||
transformers>=5.4,<6
|
||||
|
||||
@@ -0,0 +1,16 @@
|
||||
"""Make the source checkout importable on every supported test runner."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
|
||||
REPOSITORY = Path(__file__).resolve().parents[1]
|
||||
for candidate in (
|
||||
REPOSITORY.parent,
|
||||
REPOSITORY.parent / "ComfyUI",
|
||||
REPOSITORY.parents[1],
|
||||
):
|
||||
if candidate.exists():
|
||||
sys.path.insert(0, str(candidate))
|
||||
@@ -0,0 +1,46 @@
|
||||
"""Validate curated Hugging Face IDs without downloading model weights.
|
||||
|
||||
This opt-in network check resolves each repository's configuration and
|
||||
processor through the installed Transformers version. It complements, but does
|
||||
not replace, the real-weight smoke tests.
|
||||
|
||||
python tests/manual_catalog_probe.py
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
|
||||
from transformers import AutoConfig, AutoProcessor
|
||||
|
||||
from ComfyUI_VLM_nodes.nodes.modern_vlm import MODEL_CATALOG
|
||||
|
||||
|
||||
def main() -> int:
|
||||
records = []
|
||||
for label, spec in MODEL_CATALOG.items():
|
||||
if not spec.small_fast or spec.gated:
|
||||
continue
|
||||
config = AutoConfig.from_pretrained(
|
||||
spec.repo_id,
|
||||
trust_remote_code=spec.trust_remote_code,
|
||||
)
|
||||
processor = AutoProcessor.from_pretrained(
|
||||
spec.repo_id,
|
||||
trust_remote_code=spec.trust_remote_code,
|
||||
)
|
||||
records.append(
|
||||
{
|
||||
"label": label,
|
||||
"repo_id": spec.repo_id,
|
||||
"model_type": config.model_type,
|
||||
"config_class": type(config).__name__,
|
||||
"processor_class": type(processor).__name__,
|
||||
}
|
||||
)
|
||||
print("CATALOG_PROBE_JSON=" + json.dumps(records, ensure_ascii=False))
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
@@ -0,0 +1,120 @@
|
||||
"""Opt-in real-weight smoke test for the Modern VLM node.
|
||||
|
||||
This is intentionally excluded from pytest because it downloads multi-gigabyte
|
||||
models. Run one checkpoint per process so CUDA and file-handle cleanup are also
|
||||
exercised:
|
||||
|
||||
python tests/manual_model_smoke.py --model "Qwen 3.5 2B"
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import time
|
||||
|
||||
import torch
|
||||
|
||||
from ComfyUI_VLM_nodes.nodes.modern_vlm import MODEL_CATALOG, ModernVLMPredictor
|
||||
|
||||
|
||||
def test_image() -> torch.Tensor:
|
||||
image = torch.zeros((1, 96, 128, 3), dtype=torch.float32)
|
||||
image[:, 20:76, 28:104, 0] = 1.0
|
||||
return image
|
||||
|
||||
|
||||
def test_video() -> torch.Tensor:
|
||||
frames = torch.zeros((4, 96, 128, 3), dtype=torch.float32)
|
||||
for index in range(4):
|
||||
left = 12 + index * 18
|
||||
frames[index, 30:66, left : left + 24, 1] = 1.0
|
||||
return frames
|
||||
|
||||
|
||||
def main() -> int:
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--model", required=True, choices=MODEL_CATALOG)
|
||||
parser.add_argument(
|
||||
"--memory-mode",
|
||||
default="ComfyUI managed (BF16)",
|
||||
choices=[
|
||||
"ComfyUI managed (BF16)",
|
||||
"4-bit NF4 (bitsandbytes)",
|
||||
"8-bit (bitsandbytes)",
|
||||
"CPU",
|
||||
],
|
||||
)
|
||||
parser.add_argument("--video", action="store_true")
|
||||
parser.add_argument("--max-new-tokens", type=int, default=48)
|
||||
args = parser.parse_args()
|
||||
|
||||
started = time.perf_counter()
|
||||
if torch.cuda.is_available():
|
||||
torch.cuda.reset_peak_memory_stats()
|
||||
free_before, total = torch.cuda.mem_get_info()
|
||||
else:
|
||||
free_before = total = 0
|
||||
|
||||
predictor = ModernVLMPredictor(
|
||||
args.model,
|
||||
"",
|
||||
args.memory_mode,
|
||||
"Auto (SDPA)",
|
||||
)
|
||||
try:
|
||||
prompt = (
|
||||
"In this four-frame video, what color object moves horizontally? "
|
||||
"Answer with the color and shape."
|
||||
if args.video
|
||||
else (
|
||||
"Describe the dominant colors, shapes, and motion in one "
|
||||
"short factual sentence."
|
||||
)
|
||||
)
|
||||
response = predictor.generate(
|
||||
None if args.video else test_image(),
|
||||
prompt,
|
||||
"",
|
||||
args.max_new_tokens,
|
||||
0.0,
|
||||
0.9,
|
||||
test_video() if args.video else None,
|
||||
2.0,
|
||||
)
|
||||
if not response.strip():
|
||||
raise RuntimeError("The model returned an empty response.")
|
||||
if args.video and "green" not in response.lower():
|
||||
raise RuntimeError(
|
||||
f"The video frames were not understood; response was: {response}"
|
||||
)
|
||||
if not args.video and "red" not in response.lower():
|
||||
raise RuntimeError(
|
||||
f"The image was not understood; response was: {response}"
|
||||
)
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if torch.cuda.is_available():
|
||||
peak = torch.cuda.max_memory_allocated()
|
||||
free_after, _ = torch.cuda.mem_get_info()
|
||||
else:
|
||||
peak = free_after = 0
|
||||
record = {
|
||||
"model": args.model,
|
||||
"repo_id": MODEL_CATALOG[args.model].repo_id,
|
||||
"memory_mode": args.memory_mode,
|
||||
"video": args.video,
|
||||
"response": response,
|
||||
"seconds": round(time.perf_counter() - started, 2),
|
||||
"cuda_total_gib": round(total / 1024**3, 2),
|
||||
"cuda_free_before_gib": round(free_before / 1024**3, 2),
|
||||
"cuda_free_after_gib": round(free_after / 1024**3, 2),
|
||||
"cuda_peak_allocated_gib": round(peak / 1024**3, 2),
|
||||
}
|
||||
print("MODEL_SMOKE_JSON=" + json.dumps(record, ensure_ascii=False))
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
@@ -0,0 +1,294 @@
|
||||
"""Opt-in real-weight smoke tests for specialized model backends.
|
||||
|
||||
Each invocation downloads and runs one real checkpoint. Keeping one model per
|
||||
process verifies teardown and prevents one backend's CUDA state from masking
|
||||
another backend's behavior.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import time
|
||||
|
||||
import torch
|
||||
|
||||
|
||||
BACKENDS = (
|
||||
"florence-base",
|
||||
"florence-large",
|
||||
"moondream2",
|
||||
"qwen2vl-2b",
|
||||
"qwen2vl-2b-video",
|
||||
"qwen2vl-7b-4bit",
|
||||
"molmo-1b",
|
||||
"molmo-7b-d-4bit",
|
||||
"molmo-7b-o-4bit",
|
||||
"kosmos2",
|
||||
"uform",
|
||||
"mcllava",
|
||||
"joytag",
|
||||
"paligemma-caption",
|
||||
"minicpm-gguf-q4",
|
||||
"audioldm2",
|
||||
)
|
||||
|
||||
|
||||
def test_image() -> torch.Tensor:
|
||||
image = torch.zeros((1, 192, 256, 3), dtype=torch.float32)
|
||||
image[:, 48:144, 56:200, 0] = 1.0
|
||||
return image
|
||||
|
||||
|
||||
def test_video() -> torch.Tensor:
|
||||
frames = torch.zeros((4, 96, 128, 3), dtype=torch.float32)
|
||||
for index in range(4):
|
||||
left = 12 + index * 18
|
||||
frames[index, 30:66, left : left + 24, 1] = 1.0
|
||||
return frames
|
||||
|
||||
|
||||
def _run(backend: str):
|
||||
image = test_image()
|
||||
prompt = "What color is the large rectangle? Answer briefly."
|
||||
|
||||
if backend.startswith("florence-"):
|
||||
from ComfyUI_VLM_nodes.nodes.florence2 import FlorencePredictor
|
||||
from ComfyUI_VLM_nodes.nodes.runtime import tensor_batch_to_pil
|
||||
|
||||
label = {
|
||||
"florence-base": "Florence-2 base FT (fast)",
|
||||
"florence-large": "Florence-2 large FT (recommended)",
|
||||
}[backend]
|
||||
predictor = FlorencePredictor(label)
|
||||
try:
|
||||
raw, parsed = predictor.run(
|
||||
tensor_batch_to_pil(image)[0],
|
||||
"<MORE_DETAILED_CAPTION>",
|
||||
"",
|
||||
96,
|
||||
3,
|
||||
)
|
||||
return {"response": raw, "parsed": parsed}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "moondream2":
|
||||
from ComfyUI_VLM_nodes.nodes.moondream2 import Moondream2Predictor
|
||||
|
||||
predictor = Moondream2Predictor()
|
||||
try:
|
||||
return {"response": predictor.generate(image, prompt)}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend.startswith("qwen2vl-"):
|
||||
from ComfyUI_VLM_nodes.nodes.qwen2vl import Qwen2VLPredictor
|
||||
|
||||
model_name, memory_mode = {
|
||||
"qwen2vl-2b": ("Qwen2-VL-2B", "ComfyUI managed (BF16)"),
|
||||
"qwen2vl-2b-video": (
|
||||
"Qwen2-VL-2B",
|
||||
"ComfyUI managed (BF16)",
|
||||
),
|
||||
"qwen2vl-7b-4bit": ("Qwen2-VL-7B", "Maximum Savings (4-bit)"),
|
||||
}[backend]
|
||||
predictor = Qwen2VLPredictor(
|
||||
model_name,
|
||||
memory_mode,
|
||||
"Auto (SDPA)",
|
||||
256 * 28 * 28,
|
||||
1280 * 28 * 28,
|
||||
)
|
||||
try:
|
||||
if backend.endswith("-video"):
|
||||
return {
|
||||
"response": predictor.generate_video(
|
||||
None,
|
||||
test_video(),
|
||||
(
|
||||
"What color object moves horizontally? Answer with "
|
||||
"the color and shape."
|
||||
),
|
||||
48,
|
||||
0.0,
|
||||
0.9,
|
||||
2.0,
|
||||
)
|
||||
}
|
||||
return {
|
||||
"response": predictor.generate_images(
|
||||
image, prompt, 48, 0.0, 0.9
|
||||
)
|
||||
}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend.startswith("molmo-"):
|
||||
from ComfyUI_VLM_nodes.nodes.molmo import MolmoPredictor
|
||||
from ComfyUI_VLM_nodes.nodes.runtime import tensor_batch_to_pil
|
||||
|
||||
model_name, memory_mode = {
|
||||
"molmo-1b": (
|
||||
"MolmoE-1B (Efficient)",
|
||||
"Full Precision (45GB+ Required)",
|
||||
),
|
||||
"molmo-7b-d-4bit": (
|
||||
"Molmo-7B-D (Best 7B)",
|
||||
"4-bit Quantized (15GB+ Required)",
|
||||
),
|
||||
"molmo-7b-o-4bit": (
|
||||
"Molmo-7B-O (Alternative 7B)",
|
||||
"4-bit Quantized (15GB+ Required)",
|
||||
),
|
||||
}[backend]
|
||||
predictor = MolmoPredictor(model_name, memory_mode, True)
|
||||
try:
|
||||
response = predictor.generate(
|
||||
tensor_batch_to_pil(image)[0], prompt, 48, 0.0, 0.9, 20
|
||||
)
|
||||
return {"response": response}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "kosmos2":
|
||||
from ComfyUI_VLM_nodes.nodes.kosmos2 import KosmosModelPredictor
|
||||
|
||||
predictor = KosmosModelPredictor()
|
||||
try:
|
||||
return {"response": predictor.generate(image, prompt, 48)}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "uform":
|
||||
from ComfyUI_VLM_nodes.nodes.uform import UformGen2QwenChat
|
||||
|
||||
predictor = UformGen2QwenChat()
|
||||
try:
|
||||
return {"response": predictor.chat(image, prompt, 48)}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "mcllava":
|
||||
from ComfyUI_VLM_nodes.nodes.mcllava import MCLLaVAModelPredictor
|
||||
|
||||
predictor = MCLLaVAModelPredictor()
|
||||
try:
|
||||
return {
|
||||
"response": predictor.generate(
|
||||
image, prompt, 0.0, 0.9, 4, 728, 48
|
||||
)
|
||||
}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "joytag":
|
||||
from ComfyUI_VLM_nodes.nodes.joytag import JoyTagPredictor
|
||||
|
||||
predictor = JoyTagPredictor()
|
||||
try:
|
||||
return {"response": predictor.predict(image, 10, 0.1)}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "paligemma-caption":
|
||||
from ComfyUI_VLM_nodes.nodes.paligemma import (
|
||||
PALIGEMMA_MODELS,
|
||||
PaliPredictor,
|
||||
)
|
||||
from ComfyUI_VLM_nodes.nodes.runtime import tensor_batch_to_pil
|
||||
|
||||
predictor = PaliPredictor(PALIGEMMA_MODELS[0], "bfloat16", "None")
|
||||
try:
|
||||
return {
|
||||
"response": predictor.generate(
|
||||
tensor_batch_to_pil(image)[0],
|
||||
"caption en",
|
||||
max_new_tokens=64,
|
||||
do_sample=False,
|
||||
)
|
||||
}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "minicpm-gguf-q4":
|
||||
from ComfyUI_VLM_nodes.nodes.minicpm import MiniCPMPredictor
|
||||
|
||||
predictor = MiniCPMPredictor("Q4_K_M (4.7GB)", 4096, -1, 8)
|
||||
try:
|
||||
return {
|
||||
"response": predictor.generate(
|
||||
image, prompt, 0.0, 0.9, 40, 1.05, 48
|
||||
)
|
||||
}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "audioldm2":
|
||||
from ComfyUI_VLM_nodes.nodes.audioldm2 import AudioLDM2Predictor
|
||||
|
||||
predictor = AudioLDM2Predictor(cpu_offload=True)
|
||||
try:
|
||||
audio, sample_rate = predictor.generate(
|
||||
"a short clean bell chime",
|
||||
"",
|
||||
1.0,
|
||||
2.5,
|
||||
123,
|
||||
1,
|
||||
2,
|
||||
)
|
||||
return {
|
||||
"response": f"audio {audio.shape}",
|
||||
"sample_rate": sample_rate,
|
||||
"finite": bool(torch.isfinite(torch.from_numpy(audio)).all()),
|
||||
}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
raise AssertionError(f"Unhandled backend: {backend}")
|
||||
|
||||
|
||||
def main() -> int:
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--backend", required=True, choices=BACKENDS)
|
||||
args = parser.parse_args()
|
||||
|
||||
started = time.perf_counter()
|
||||
if torch.cuda.is_available():
|
||||
torch.cuda.reset_peak_memory_stats()
|
||||
free_before, total = torch.cuda.mem_get_info()
|
||||
else:
|
||||
free_before = total = 0
|
||||
|
||||
result = _run(args.backend)
|
||||
response = str(result.get("response", ""))
|
||||
if not response.strip():
|
||||
raise RuntimeError("The model returned an empty response.")
|
||||
expected = "green" if args.backend.endswith("-video") else "red"
|
||||
if args.backend != "audioldm2" and expected not in response.lower():
|
||||
raise RuntimeError(
|
||||
f"The model did not identify the {expected} test object: {response}"
|
||||
)
|
||||
if args.backend == "audioldm2" and not result["finite"]:
|
||||
raise RuntimeError("AudioLDM2 returned non-finite samples.")
|
||||
|
||||
if torch.cuda.is_available():
|
||||
peak = torch.cuda.max_memory_allocated()
|
||||
free_after, _ = torch.cuda.mem_get_info()
|
||||
else:
|
||||
peak = free_after = 0
|
||||
result.update(
|
||||
backend=args.backend,
|
||||
seconds=round(time.perf_counter() - started, 2),
|
||||
cuda_total_gib=round(total / 1024**3, 2),
|
||||
cuda_free_before_gib=round(free_before / 1024**3, 2),
|
||||
cuda_free_after_gib=round(free_after / 1024**3, 2),
|
||||
cuda_peak_allocated_gib=round(peak / 1024**3, 2),
|
||||
)
|
||||
print("SPECIALIZED_SMOKE_JSON=" + json.dumps(result, ensure_ascii=False, default=str))
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
@@ -0,0 +1,330 @@
|
||||
import base64
|
||||
import inspect
|
||||
import io
|
||||
from pathlib import Path
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
import torch
|
||||
from PIL import Image
|
||||
|
||||
import ComfyUI_VLM_nodes as package
|
||||
from ComfyUI_VLM_nodes.nodes import (
|
||||
audioldm2,
|
||||
florence2,
|
||||
modern_vlm,
|
||||
paligemma,
|
||||
qwen2vl,
|
||||
)
|
||||
from ComfyUI_VLM_nodes.nodes.runtime import (
|
||||
accelerator_backend,
|
||||
external_device_map,
|
||||
image_data_uri,
|
||||
pil_mask_to_tensor,
|
||||
pil_to_tensor,
|
||||
runtime_diagnostics,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
|
||||
def test_every_module_imports_and_expected_nodes_exist():
|
||||
assert package.IMPORT_ERRORS == {}
|
||||
expected = {
|
||||
"ModernVLM",
|
||||
"VLMRuntimeDiagnostics",
|
||||
"Florence2",
|
||||
"Paligemma",
|
||||
"MolmoNode",
|
||||
"Qwen2VLNode",
|
||||
"Moondream2model",
|
||||
"MiniCPMNode",
|
||||
}
|
||||
assert expected <= package.NODE_CLASS_MAPPINGS.keys()
|
||||
|
||||
|
||||
def test_node_schemas_do_not_use_force_input():
|
||||
for node_class in package.NODE_CLASS_MAPPINGS.values():
|
||||
schema = node_class.INPUT_TYPES()
|
||||
assert "forceInput" not in repr(schema)
|
||||
|
||||
|
||||
def test_source_has_no_runtime_installer_or_direct_cuda_cache():
|
||||
root = Path(package.__file__).parent
|
||||
source = "\n".join(
|
||||
path.read_text(encoding="utf-8", errors="replace")
|
||||
for path in (root / "nodes").rglob("*.py")
|
||||
)
|
||||
assert "torch.cuda.empty_cache" not in source
|
||||
assert "subprocess.run" not in source
|
||||
assert "pip install" not in source
|
||||
|
||||
|
||||
def test_portable_device_dtype_and_backend_contracts(monkeypatch):
|
||||
assert torch_dtype("float16", torch.device("cpu")) == torch.float32
|
||||
assert torch_dtype("float16", torch.device("mps")) == torch.float16
|
||||
assert torch_dtype("float16", torch.device("xpu")) == torch.float16
|
||||
assert accelerator_backend(torch.device("mps")) == "apple-metal"
|
||||
assert accelerator_backend(torch.device("xpu")) == "intel-xpu"
|
||||
|
||||
monkeypatch.setattr(torch.version, "hip", None, raising=False)
|
||||
assert accelerator_backend(torch.device("cuda")) == "nvidia-cuda"
|
||||
monkeypatch.setattr(torch.version, "hip", "7.2", raising=False)
|
||||
assert accelerator_backend(torch.device("cuda")) == "amd-rocm"
|
||||
|
||||
|
||||
def test_runtime_report_and_device_map_are_supportable():
|
||||
report = runtime_diagnostics()
|
||||
assert {
|
||||
"platform",
|
||||
"machine",
|
||||
"python",
|
||||
"torch",
|
||||
"device",
|
||||
"backend",
|
||||
"bf16",
|
||||
"torch_cuda",
|
||||
"torch_hip",
|
||||
"packages",
|
||||
} <= report.keys()
|
||||
device_map = external_device_map()
|
||||
assert set(device_map) == {""}
|
||||
assert device_map[""] == report["device"]
|
||||
|
||||
|
||||
def test_dependency_metadata_matches_installer_requirements():
|
||||
try:
|
||||
import tomllib
|
||||
except ModuleNotFoundError:
|
||||
pytest.skip("tomllib is built into Python 3.11+")
|
||||
from packaging.requirements import Requirement
|
||||
|
||||
root = Path(package.__file__).parent
|
||||
metadata = tomllib.loads((root / "pyproject.toml").read_text("utf-8"))
|
||||
project_requirements = {
|
||||
str(Requirement(value)) for value in metadata["project"]["dependencies"]
|
||||
}
|
||||
installer_requirements = {
|
||||
str(Requirement(line))
|
||||
for line in (root / "requirements.txt").read_text("utf-8").splitlines()
|
||||
if line.strip() and not line.lstrip().startswith("#")
|
||||
}
|
||||
assert project_requirements == installer_requirements
|
||||
|
||||
bitsandbytes = next(
|
||||
Requirement(value)
|
||||
for value in metadata["project"]["dependencies"]
|
||||
if Requirement(value).name == "bitsandbytes"
|
||||
)
|
||||
assert bitsandbytes.marker is not None
|
||||
supported = (
|
||||
("linux", "x86_64"),
|
||||
("linux", "aarch64"),
|
||||
("win32", "AMD64"),
|
||||
("win32", "ARM64"),
|
||||
("darwin", "arm64"),
|
||||
)
|
||||
unsupported = (
|
||||
("darwin", "x86_64"),
|
||||
("linux", "ppc64le"),
|
||||
)
|
||||
for system, machine in supported:
|
||||
assert bitsandbytes.marker.evaluate(
|
||||
{"sys_platform": system, "platform_machine": machine}
|
||||
)
|
||||
for system, machine in unsupported:
|
||||
assert not bitsandbytes.marker.evaluate(
|
||||
{"sys_platform": system, "platform_machine": machine}
|
||||
)
|
||||
|
||||
|
||||
def test_image_roundtrip_and_png_data_uri():
|
||||
tensor = torch.tensor(
|
||||
[[[[0.0, 0.5, 1.0], [1.0, float("nan"), 0.0]]]],
|
||||
dtype=torch.float32,
|
||||
)
|
||||
images = tensor_batch_to_pil(tensor)
|
||||
assert images[0].size == (2, 1)
|
||||
uri = image_data_uri(images[0])
|
||||
payload = base64.b64decode(uri.split(",", 1)[1])
|
||||
assert Image.open(io.BytesIO(payload)).format == "PNG"
|
||||
assert pil_to_tensor(images[0]).shape == (1, 1, 2, 3)
|
||||
assert pil_mask_to_tensor(Image.new("L", (2, 3))).shape == (1, 3, 2)
|
||||
|
||||
|
||||
def test_paligemma_parser_uses_normalized_boxes_and_16_codes():
|
||||
codes = "".join(f"<seg{index:03d}>" for index in range(16))
|
||||
parsed = paligemma.parse_segments(
|
||||
f"<loc0100><loc0200><loc0900><loc0800>{codes} cat"
|
||||
)
|
||||
assert len(parsed) == 1
|
||||
box, values, label = parsed[0]
|
||||
assert box == pytest.approx((100 / 1024, 200 / 1024, 900 / 1024, 800 / 1024))
|
||||
assert values == list(range(16))
|
||||
assert label == "cat"
|
||||
|
||||
|
||||
def test_florence_rendering_supports_boxes_quads_and_nested_polygons():
|
||||
image = Image.new("RGB", (32, 24), "black")
|
||||
parsed = {
|
||||
"<TASK>": {
|
||||
"bboxes": [[1, 1, 10, 10]],
|
||||
"labels": ["box"],
|
||||
"quad_boxes": [[2, 2, 8, 2, 8, 8, 2, 8]],
|
||||
"polygons": [[[4, 4, 20, 4, 20, 20, 4, 20]]],
|
||||
}
|
||||
}
|
||||
mask, visual = florence2._visualize(image, parsed)
|
||||
assert np.asarray(mask).max() == 255
|
||||
assert visual.size == image.size
|
||||
|
||||
|
||||
def test_modern_catalog_has_current_quality_and_low_vram_tiers():
|
||||
repositories = {spec.repo_id for spec in modern_vlm.MODEL_CATALOG.values()}
|
||||
small_fast = [
|
||||
spec for spec in modern_vlm.MODEL_CATALOG.values() if spec.small_fast
|
||||
]
|
||||
assert 10 <= len(small_fast) <= 20
|
||||
assert all(
|
||||
not spec.trust_remote_code
|
||||
for spec in modern_vlm.MODEL_CATALOG.values()
|
||||
if spec.family != "Custom"
|
||||
)
|
||||
assert modern_vlm.MODEL_CATALOG[
|
||||
"Custom Hugging Face model"
|
||||
].trust_remote_code
|
||||
assert "Qwen/Qwen3.5-4B" in repositories
|
||||
assert "Qwen/Qwen3.5-35B-A3B" in repositories
|
||||
assert "Qwen/Qwen3.6-27B" in repositories
|
||||
assert "Qwen/Qwen3-VL-8B-Instruct" in repositories
|
||||
assert "Qwen/Qwen2.5-VL-3B-Instruct" in repositories
|
||||
assert "google/gemma-3-4b-it" in repositories
|
||||
assert "HuggingFaceTB/SmolVLM2-256M-Video-Instruct" in repositories
|
||||
assert "HuggingFaceTB/SmolVLM2-500M-Video-Instruct" in repositories
|
||||
assert "LiquidAI/LFM2.5-VL-450M" in repositories
|
||||
assert "LiquidAI/LFM2.5-VL-1.6B" in repositories
|
||||
assert "OpenGVLab/InternVL3_5-1B-HF" in repositories
|
||||
assert "OpenGVLab/InternVL3_5-2B-HF" in repositories
|
||||
assert "ibm-granite/granite-vision-3.3-2b" in repositories
|
||||
assert "ibm-granite/granite-vision-4.1-4b" in repositories
|
||||
|
||||
|
||||
def test_modern_video_is_primary_input_and_thinking_is_explicit():
|
||||
assert "image" in modern_vlm.ModernVLM.INPUT_TYPES()["optional"]
|
||||
assert "image" in qwen2vl.Qwen2VLNode.INPUT_TYPES()["optional"]
|
||||
predictor = modern_vlm.ModernVLMPredictor.__new__(
|
||||
modern_vlm.ModernVLMPredictor
|
||||
)
|
||||
predictor.spec = modern_vlm.ModelSpec(
|
||||
"test/model", "Qwen 3.5", 1.0, video=True
|
||||
)
|
||||
captured = {}
|
||||
|
||||
def capture(messages, enable_thinking=False, **kwargs):
|
||||
captured["messages"] = messages
|
||||
captured["enable_thinking"] = enable_thinking
|
||||
captured.update(kwargs)
|
||||
raise RuntimeError("captured before inference")
|
||||
|
||||
predictor._inputs = capture
|
||||
frames = torch.zeros((4, 8, 8, 3), dtype=torch.float32)
|
||||
with pytest.raises(RuntimeError, match="captured before inference"):
|
||||
predictor.generate(
|
||||
None,
|
||||
"What moves?",
|
||||
"",
|
||||
8,
|
||||
0.0,
|
||||
0.9,
|
||||
frames,
|
||||
2.0,
|
||||
True,
|
||||
)
|
||||
|
||||
content = captured["messages"][-1]["content"]
|
||||
assert [part["type"] for part in content] == ["video", "text"]
|
||||
assert len(content[0]["video"]) == 4
|
||||
assert "2 FPS" in content[1]["text"]
|
||||
assert captured["enable_thinking"] is True
|
||||
assert captured["video_metadata"]["fps"] == 2.0
|
||||
assert captured["video_metadata"]["frames_indices"] == [0, 1, 2, 3]
|
||||
|
||||
|
||||
def test_internvl_video_uses_an_even_vision_patch_grid():
|
||||
predictor = modern_vlm.ModernVLMPredictor.__new__(
|
||||
modern_vlm.ModernVLMPredictor
|
||||
)
|
||||
predictor.spec = modern_vlm.ModelSpec(
|
||||
"test/model", "InternVL 3.5", 1.0, video=True
|
||||
)
|
||||
captured = {}
|
||||
|
||||
class ImageProcessor:
|
||||
size = {"height": 448, "width": 448}
|
||||
|
||||
class Processor:
|
||||
image_processor = ImageProcessor()
|
||||
|
||||
def apply_chat_template(self, _messages, **kwargs):
|
||||
captured.update(kwargs)
|
||||
return {"input_ids": torch.ones((1, 1), dtype=torch.long)}
|
||||
|
||||
predictor.processor = Processor()
|
||||
predictor._inputs(
|
||||
[{"role": "user", "content": [{"type": "text", "text": "test"}]}],
|
||||
video_metadata={"fps": 2.0},
|
||||
)
|
||||
assert captured["processor_kwargs"]["size"] == {
|
||||
"height": 448,
|
||||
"width": 448,
|
||||
}
|
||||
|
||||
|
||||
def test_qwen2_legacy_quantized_labels_use_maintained_backends():
|
||||
assert list(qwen2vl.QWEN2_VL_CHOICES) == [
|
||||
"Qwen2-VL-2B",
|
||||
"Qwen2-VL-7B",
|
||||
]
|
||||
assert qwen2vl.LEGACY_QUANTIZED_ALIASES[
|
||||
"Qwen2-VL-7B-GPTQ-Int8"
|
||||
] == ("Qwen2-VL-7B", "Balanced (8-bit)")
|
||||
assert qwen2vl.LEGACY_QUANTIZED_ALIASES[
|
||||
"Qwen2-VL-7B-AWQ"
|
||||
] == ("Qwen2-VL-7B", "Maximum Savings (4-bit)")
|
||||
|
||||
|
||||
def test_audioldm_keeps_legacy_outputs_and_adds_standard_audio(monkeypatch):
|
||||
class FakePredictor:
|
||||
def generate(self, *_args):
|
||||
return np.zeros((2, 16), dtype=np.float32), 16000
|
||||
|
||||
node = audioldm2.AudioLDM2Node()
|
||||
monkeypatch.setattr(node, "get_or_create_model", lambda *_args: FakePredictor())
|
||||
result = node.generate_audio_final(
|
||||
"rain", "", 1, 3.5, 16000, 42, 2, "wav"
|
||||
)
|
||||
assert len(result) == 3
|
||||
assert result[1] == 16000
|
||||
assert result[2]["waveform"].shape == (2, 1, 16)
|
||||
|
||||
|
||||
def test_node_functions_accept_every_declared_input_name():
|
||||
for node_class in package.NODE_CLASS_MAPPINGS.values():
|
||||
function = getattr(node_class, node_class.FUNCTION)
|
||||
signature = inspect.signature(function)
|
||||
if any(
|
||||
parameter.kind == inspect.Parameter.VAR_KEYWORD
|
||||
for parameter in signature.parameters.values()
|
||||
):
|
||||
continue
|
||||
declared = {
|
||||
name
|
||||
for group in node_class.INPUT_TYPES().values()
|
||||
if isinstance(group, dict)
|
||||
for name in group
|
||||
}
|
||||
accepted = set(signature.parameters)
|
||||
assert declared <= accepted, (
|
||||
node_class.__name__,
|
||||
declared - accepted,
|
||||
)
|
||||
+53
-37
@@ -1,42 +1,58 @@
|
||||
import { app } from "../../../scripts/app.js";
|
||||
import { ComfyWidgets } from "../../../scripts/widgets.js";
|
||||
|
||||
const OUTPUT_NAME = "formatted_text";
|
||||
|
||||
function ensureOutputWidget(node) {
|
||||
let widget = node.widgets?.find((item) => item.name === OUTPUT_NAME);
|
||||
if (!widget) {
|
||||
const output = document.createElement("textarea");
|
||||
output.readOnly = true;
|
||||
output.setAttribute("aria-label", "Formatted JSON text output");
|
||||
Object.assign(output.style, {
|
||||
width: "100%",
|
||||
height: "100%",
|
||||
minHeight: "120px",
|
||||
resize: "vertical",
|
||||
boxSizing: "border-box",
|
||||
color: "var(--input-text, #ddd)",
|
||||
background: "var(--comfy-input-bg, #202020)",
|
||||
border: "1px solid var(--border-color, #555)",
|
||||
borderRadius: "6px",
|
||||
padding: "8px",
|
||||
});
|
||||
widget = node.addDOMWidget(OUTPUT_NAME, "STRING", output, {
|
||||
serialize: false,
|
||||
hideOnZoom: false,
|
||||
});
|
||||
widget.serialize = false;
|
||||
widget.inputEl = output;
|
||||
}
|
||||
return widget;
|
||||
}
|
||||
|
||||
app.registerExtension({
|
||||
name: "n.JsonToText",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData, app) {
|
||||
|
||||
if (nodeData.name === "JsonToText") {
|
||||
console.warn("JsonToText");
|
||||
|
||||
const onExecuted = nodeType.prototype.onExecuted;
|
||||
|
||||
nodeType.prototype.onExecuted = function (message) {
|
||||
if (this.widgets) {
|
||||
for (let i = 1; i < this.widgets.length; i++) {
|
||||
this.widgets[i].onRemove?.();
|
||||
}
|
||||
this.widgets.length = 1;
|
||||
}
|
||||
|
||||
// Call the original onExecuted method if it exists.
|
||||
onExecuted?.apply(this, arguments);
|
||||
|
||||
// Check if the "text" widget already exists.
|
||||
let textWidget = this.widgets.find(w => w.name === "newtext");
|
||||
if (!textWidget) {
|
||||
// If the "text" widget does not exist, create it.
|
||||
textWidget = ComfyWidgets["STRING"](this, "newtext", ["STRING", { multiline: true }], app).widget;
|
||||
}
|
||||
|
||||
// Generate a random number and set it as the value of the "text" widget.
|
||||
|
||||
textWidget.inputEl.readOnly = true;
|
||||
textWidget.inputEl.style.opacity = 0.6;
|
||||
textWidget.value = message["text"].join("");
|
||||
// change color of the widget
|
||||
console.log(message)
|
||||
|
||||
};
|
||||
name: "gokayfem.vlm.json-to-text",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData) {
|
||||
if (nodeData.name !== "JsonToText") {
|
||||
return;
|
||||
}
|
||||
const onCreated = nodeType.prototype.onNodeCreated;
|
||||
nodeType.prototype.onNodeCreated = function (...args) {
|
||||
const result = onCreated?.apply(this, args);
|
||||
ensureOutputWidget(this);
|
||||
return result;
|
||||
};
|
||||
const onExecuted = nodeType.prototype.onExecuted;
|
||||
nodeType.prototype.onExecuted = function (message) {
|
||||
const result = onExecuted?.apply(this, arguments);
|
||||
const values = Array.isArray(message?.text)
|
||||
? message.text
|
||||
: [message?.text ?? ""];
|
||||
const widget = ensureOutputWidget(this);
|
||||
widget.value = values.join("");
|
||||
widget.inputEl.value = widget.value;
|
||||
this.setDirtyCanvas?.(true, true);
|
||||
return result;
|
||||
};
|
||||
},
|
||||
});
|
||||
});
|
||||
|
||||
+51
-49
@@ -1,55 +1,57 @@
|
||||
import { app } from "../../../scripts/app.js";
|
||||
|
||||
app.registerExtension({
|
||||
name: "n.PlayMusic",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData, app) {
|
||||
if (nodeData.name === "PlayMusic") {
|
||||
console.warn("PlayMusic");
|
||||
const onExecuted = nodeType.prototype.onExecuted;
|
||||
nodeType.prototype.onExecuted = async function () {
|
||||
onExecuted?.apply(this, arguments);
|
||||
function firstValue(value) {
|
||||
return Array.isArray(value) && value.length === 1 ? value[0] : value;
|
||||
}
|
||||
|
||||
// Check for "on empty queue" condition, if applicable
|
||||
if (this.widgets[0].value === "on empty queue") {
|
||||
if (app.ui.lastQueueSize !== 0) {
|
||||
await new Promise((r) => setTimeout(r, 500));
|
||||
}
|
||||
if (app.ui.lastQueueSize !== 0) {
|
||||
return;
|
||||
}
|
||||
}
|
||||
|
||||
// Assuming that 'arguments[0].a' is the waveform and 'arguments[0].b' is the sample rate
|
||||
let waveform = arguments[0].a; // An array of floats (-1 to 1)
|
||||
let sampleRate = arguments[0].b; // The sample rate of the audio
|
||||
console.log(waveform, sampleRate);
|
||||
// Create AudioContext
|
||||
let audioCtx = new (window.AudioContext || window.webkitAudioContext)({sampleRate: sampleRate});
|
||||
|
||||
// Create AudioBuffer
|
||||
let buffer = audioCtx.createBuffer(1, waveform[0].length, sampleRate);
|
||||
|
||||
// Fill the AudioBuffer
|
||||
buffer.getChannelData(0).set(waveform[0]);
|
||||
|
||||
// Create a source and connect it to the buffer
|
||||
let source = audioCtx.createBufferSource();
|
||||
source.buffer = buffer;
|
||||
source.connect(audioCtx.destination);
|
||||
|
||||
// Set volume, if applicable. Assuming the volume is the second widget's value.
|
||||
let volume = this.widgets[1].value;
|
||||
if (volume !== undefined) {
|
||||
let gainNode = audioCtx.createGain();
|
||||
gainNode.gain.value = volume;
|
||||
source.connect(gainNode);
|
||||
gainNode.connect(audioCtx.destination);
|
||||
}
|
||||
|
||||
// Play the sound
|
||||
source.start();
|
||||
};
|
||||
app.registerExtension({
|
||||
name: "gokayfem.vlm.play-music",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData) {
|
||||
if (nodeData.name !== "PlayMusic") {
|
||||
return;
|
||||
}
|
||||
const onExecuted = nodeType.prototype.onExecuted;
|
||||
nodeType.prototype.onExecuted = async function (message) {
|
||||
onExecuted?.apply(this, arguments);
|
||||
const mode = firstValue(this.widgets?.[0]?.value) ?? "always";
|
||||
if (mode === "on empty queue" && (app.ui?.lastQueueSize ?? 0) > 0) {
|
||||
return;
|
||||
}
|
||||
|
||||
const raw = firstValue(message?.a);
|
||||
const samples = Array.isArray(raw?.[0]) ? raw[0] : raw;
|
||||
const sampleRate = Number(firstValue(message?.b));
|
||||
if (!samples?.length || !Number.isFinite(sampleRate)) {
|
||||
return;
|
||||
}
|
||||
|
||||
this.__vlmAudioSource?.stop?.();
|
||||
const AudioContext = window.AudioContext ?? window.webkitAudioContext;
|
||||
this.__vlmAudioContext ??= new AudioContext({ sampleRate });
|
||||
await this.__vlmAudioContext.resume();
|
||||
const buffer = this.__vlmAudioContext.createBuffer(
|
||||
1,
|
||||
samples.length,
|
||||
sampleRate,
|
||||
);
|
||||
buffer.getChannelData(0).set(samples);
|
||||
const source = this.__vlmAudioContext.createBufferSource();
|
||||
const gain = this.__vlmAudioContext.createGain();
|
||||
gain.gain.value = Number(firstValue(this.widgets?.[1]?.value) ?? 0.5);
|
||||
source.buffer = buffer;
|
||||
source.connect(gain);
|
||||
gain.connect(this.__vlmAudioContext.destination);
|
||||
source.start();
|
||||
this.__vlmAudioSource = source;
|
||||
};
|
||||
|
||||
const onRemoved = nodeType.prototype.onRemoved;
|
||||
nodeType.prototype.onRemoved = function (...args) {
|
||||
this.__vlmAudioSource?.stop?.();
|
||||
void this.__vlmAudioContext?.close?.();
|
||||
this.__vlmAudioSource = null;
|
||||
this.__vlmAudioContext = null;
|
||||
return onRemoved?.apply(this, args);
|
||||
};
|
||||
},
|
||||
});
|
||||
|
||||
|
||||
+53
-37
@@ -1,42 +1,58 @@
|
||||
import { app } from "../../../scripts/app.js";
|
||||
import { ComfyWidgets } from "../../../scripts/widgets.js";
|
||||
|
||||
const OUTPUT_NAME = "output_text";
|
||||
|
||||
function ensureOutputWidget(node) {
|
||||
let widget = node.widgets?.find((item) => item.name === OUTPUT_NAME);
|
||||
if (!widget) {
|
||||
const output = document.createElement("textarea");
|
||||
output.readOnly = true;
|
||||
output.setAttribute("aria-label", "VLM text output");
|
||||
Object.assign(output.style, {
|
||||
width: "100%",
|
||||
height: "100%",
|
||||
minHeight: "120px",
|
||||
resize: "vertical",
|
||||
boxSizing: "border-box",
|
||||
color: "var(--input-text, #ddd)",
|
||||
background: "var(--comfy-input-bg, #202020)",
|
||||
border: "1px solid var(--border-color, #555)",
|
||||
borderRadius: "6px",
|
||||
padding: "8px",
|
||||
});
|
||||
widget = node.addDOMWidget(OUTPUT_NAME, "STRING", output, {
|
||||
serialize: false,
|
||||
hideOnZoom: false,
|
||||
});
|
||||
widget.serialize = false;
|
||||
widget.inputEl = output;
|
||||
}
|
||||
return widget;
|
||||
}
|
||||
|
||||
app.registerExtension({
|
||||
name: "n.ViewText",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData, app) {
|
||||
|
||||
if (nodeData.name === "ViewText") {
|
||||
console.warn("ViewText");
|
||||
|
||||
const onExecuted = nodeType.prototype.onExecuted;
|
||||
|
||||
nodeType.prototype.onExecuted = function (message) {
|
||||
if (this.widgets) {
|
||||
for (let i = 1; i < this.widgets.length; i++) {
|
||||
this.widgets[i].onRemove?.();
|
||||
}
|
||||
this.widgets.length = 1;
|
||||
}
|
||||
|
||||
// Call the original onExecuted method if it exists.
|
||||
onExecuted?.apply(this, arguments);
|
||||
|
||||
// Check if the "text" widget already exists.
|
||||
let textWidget = this.widgets.find(w => w.name === "new_text");
|
||||
if (!textWidget) {
|
||||
// If the "text" widget does not exist, create it.
|
||||
textWidget = ComfyWidgets["STRING"](this, "new_text", ["STRING", { multiline: true }], app).widget;
|
||||
}
|
||||
|
||||
// Generate a random number and set it as the value of the "text" widget.
|
||||
|
||||
textWidget.inputEl.readOnly = true;
|
||||
textWidget.inputEl.style.opacity = 0.6;
|
||||
textWidget.value = message["text"].join("");
|
||||
// change color of the widget
|
||||
console.log(message)
|
||||
|
||||
};
|
||||
name: "gokayfem.vlm.view-text",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData) {
|
||||
if (nodeData.name !== "ViewText") {
|
||||
return;
|
||||
}
|
||||
const onCreated = nodeType.prototype.onNodeCreated;
|
||||
nodeType.prototype.onNodeCreated = function (...args) {
|
||||
const result = onCreated?.apply(this, args);
|
||||
ensureOutputWidget(this);
|
||||
return result;
|
||||
};
|
||||
const onExecuted = nodeType.prototype.onExecuted;
|
||||
nodeType.prototype.onExecuted = function (message) {
|
||||
const result = onExecuted?.apply(this, arguments);
|
||||
const values = Array.isArray(message?.text)
|
||||
? message.text
|
||||
: [message?.text ?? ""];
|
||||
const widget = ensureOutputWidget(this);
|
||||
widget.value = values.join("");
|
||||
widget.inputEl.value = widget.value;
|
||||
this.setDirtyCanvas?.(true, true);
|
||||
return result;
|
||||
};
|
||||
},
|
||||
});
|
||||
});
|
||||
|
||||
Reference in New Issue
Block a user