Compare commits
148
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Gokay Aydogan |
c13ee2364e | ||
|
gokayfem
|
b8ae298abf | ||
|
Gökay Aydoğan
|
bb7d51777c | ||
|
gokayfem
|
102f1662ac | ||
|
Gökay Aydoğan
|
44fefcb57a | ||
|
Gökay Aydoğan
|
505b324f66 | ||
|
Gökay Aydoğan
|
39fc116341 | ||
|
gokayfem
|
239c9045ab | ||
|
gokayfem
|
0da5070039 | ||
|
gokayfem
|
4c200c4dda | ||
|
gokayfem
|
58fd4823b9 | ||
|
gokayfem
|
2efd3631b8 | ||
|
gokayfem
|
bcb756d973 | ||
|
gokayfem
|
37317a8478 | ||
|
gokayfem
|
460b27a1b5 | ||
|
gokayfem
|
1e04a56444 | ||
|
gokayfem
|
b89f6288bb | ||
|
Gökay Aydoğan
|
066b10fd60 | ||
|
Gökay Aydoğan
|
eabca719dd | ||
|
Gökay Aydoğan
|
8bd18dd52b | ||
|
mavibirdesmi
|
858ab8a13e | ||
|
Gökay Aydoğan
|
1ca496c1c8 | ||
|
Juggernaut
|
7174a2ac91 | ||
|
Juggernaut
|
77f70e4417 | ||
|
Gökay Aydoğan
|
320cf09f6c | ||
|
Gökay Aydoğan
|
59ead9f513 | ||
|
EnragedAntelope
|
6817bdba01 | ||
|
EnragedAntelope
|
724a787eae | ||
|
EnragedAntelope
|
7f5bc8956b | ||
|
Gökay Aydoğan
|
52e20049e8 | ||
|
Gökay Aydoğan
|
babc604703 | ||
|
EnragedAntelope
|
83ce962b94 | ||
|
EnragedAntelope
|
cf463e3590 | ||
|
EnragedAntelope
|
d977b2c106 | ||
|
gokayfem
|
0bfaad3a91 | ||
|
gokayfem
|
bfa702a282 | ||
|
gokayfem
|
e1a48dbaa4 | ||
|
gokayfem
|
7817b69fe3 | ||
|
Gökay Aydoğan
|
bd8975fbdc | ||
|
Gökay Aydoğan
|
b09fdb6e02 | ||
|
Gökay Aydoğan
|
372a8448f6 | ||
|
gokayfem
|
63e9e20625 | ||
|
Gökay Aydoğan
|
80d1f30a99 | ||
|
Gökay Aydoğan
|
1cc82e14b5 | ||
|
Gökay Aydoğan
|
68b8966f1b | ||
|
gokayfem
|
f260a590ba | ||
|
Gökay Aydoğan
|
27f72e532a | ||
|
gokayfem
|
4469d7a19f | ||
|
EnragedAntelope
|
a8f60dd44f | ||
|
EnragedAntelope
|
eccdb0e0d4 | ||
|
EnragedAntelope
|
1cf85b8f63 | ||
|
Gökay Aydoğan
|
a5ceb90f48 | ||
|
EnragedAntelope
|
9723f506a3 | ||
|
EnragedAntelope
|
40f25f55aa | ||
|
Gökay Aydoğan
|
400fded7af | ||
|
EnragedAntelope
|
6d76b29f71 | ||
|
Gökay Aydoğan
|
043dfbe727 | ||
|
Gökay Aydoğan
|
57d6060cd1 | ||
|
default
|
3df8e96adf | ||
|
Gökay Aydoğan
|
aee755b26a | ||
|
Gökay Aydoğan
|
8506a8e1f2 | ||
|
Yoland Yan
|
12b550516e | ||
|
Yoland Yan
|
04fec51386 | ||
|
Gökay Aydoğan
|
a3caf32dba | ||
|
Gökay Aydoğan
|
711801166b | ||
|
snomiao
|
f45e1456ee | ||
|
Gökay Aydoğan
|
260316eacb | ||
|
Gökay Aydoğan
|
d6bb765089 | ||
|
Gökay Aydoğan
|
7979ae79a9 | ||
|
Gökay Aydoğan
|
ab0ea30a11 | ||
|
gokayfem
|
114e71d4c2 | ||
|
gokayfem
|
2d289c3c9f | ||
|
Gökay Aydoğan
|
fc5ddf6d05 | ||
|
Gökay Aydoğan
|
f5e3a896e9 | ||
|
Gökay Aydoğan
|
5a4f077c60 | ||
|
haohaocreates
|
81bee12a68 | ||
|
Gökay Aydoğan
|
e2c711422e | ||
|
Gökay Aydoğan
|
69a774f786 | ||
|
Gökay Aydoğan
|
95b2d039fd | ||
|
Gökay Aydoğan
|
3636697f2f | ||
|
haohaocreates
|
ebb34be2cc | ||
|
null
|
431f2623c3 | ||
|
Wouter de Bie
|
546164cc5e | ||
|
Gökay Aydoğan
|
abb2838db1 | ||
|
gokayfem
|
3836e67cd1 | ||
|
Torbjörn Lönnemark
|
5b46de997c | ||
|
gokayfem
|
ebceeac0ee | ||
|
gokayfem
|
c094952b51 | ||
|
gokayfem
|
54b5c1024e | ||
|
SKB
|
bea554556a | ||
|
SKB
|
a4f1223689 | ||
|
SKB
|
ff3814fc5a | ||
|
gokayfem
|
d1770aa931 | ||
|
gokayfem
|
af77cc2790 | ||
|
gokayfem
|
fe20baaa2d | ||
|
gokayfem
|
a8aa176fb5 | ||
|
gokayfem
|
26bd276105 | ||
|
gokayfem
|
c202ae481c | ||
|
gokayfem
|
684f05f012 | ||
|
gokayfem
|
ad7398467d | ||
|
gokayfem
|
8f918d07db | ||
|
gokayfem
|
e04019e22b | ||
|
gokayfem
|
21c13d8232 | ||
|
gokayfem
|
873ccd3d6b | ||
|
gokayfem
|
e352ff52b6 | ||
|
gokayfem
|
6600b13f9e | ||
|
gokayfem
|
470b347c48 | ||
|
gokayfem
|
1fe7a608d6 | ||
|
gokayfem
|
4048e74841 | ||
|
gokayfem
|
5bc422b372 | ||
|
gokayfem
|
3d72d9bbd1 | ||
|
gokayfem
|
a363153eb5 | ||
|
gokayfem
|
6e043f44f6 | ||
|
gokayfem
|
12dff74965 | ||
|
gokayfem
|
ab0ff641e8 | ||
|
gokayfem
|
ae9ef30c4c | ||
|
gokayfem
|
6d2c2f84d8 | ||
|
gokayfem
|
70bdb2b883 | ||
|
gokayfem
|
6765b6ea11 | ||
|
gokayfem
|
cac0f8d22a | ||
|
gokayfem
|
fc88d71179 | ||
|
gokayfem
|
39885c9246 | ||
|
gokayfem
|
640fb70f33 | ||
|
gokayfem
|
5dee27bd9b | ||
|
gokayfem
|
dc262a9683 | ||
|
gokayfem
|
3a95355d05 | ||
|
gokayfem
|
e452c0ea91 | ||
|
gokayfem
|
1444dbb346 | ||
|
gokayfem
|
899b894435 | ||
|
gokayfem
|
c2850d8e7a | ||
|
gokayfem
|
a829cf4932 | ||
|
gokayfem
|
64da5b1506 | ||
|
gokayfem
|
f1438415f7 | ||
|
gokayfem
|
fd65743f13 | ||
|
gokayfem
|
777933600e | ||
|
gokayfem
|
6f9b156f24 | ||
|
gokayfem
|
08c743d2ae | ||
|
gokayfem
|
c920a4e714 | ||
|
gokayfem
|
9d15d4567b | ||
|
gokayfem
|
f091d411f7 | ||
|
gokayfem
|
ce9abb3bd9 | ||
|
gokayfem
|
16eb505136 | ||
|
gokayfem
|
4de8baaaaf | ||
|
gokayfem
|
b57aa3ada9 | ||
|
gokayfem
|
b22479ac71 | ||
|
gokayfem
|
9c6aef69a0 | ||
|
gokayfem
|
8d4c8549c6 | ||
|
gokayfem
|
3d03ddeb9c |
@@ -0,0 +1,62 @@
|
||||
name: CI
|
||||
|
||||
on:
|
||||
push:
|
||||
pull_request:
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
test:
|
||||
name: ${{ matrix.label }}
|
||||
runs-on: ${{ matrix.os }}
|
||||
timeout-minutes: 35
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
include:
|
||||
- label: Linux / Python 3.10
|
||||
os: ubuntu-latest
|
||||
python: "3.10"
|
||||
cpu_index: true
|
||||
- label: Linux / Python 3.13
|
||||
os: ubuntu-latest
|
||||
python: "3.13"
|
||||
cpu_index: true
|
||||
- label: Windows / Python 3.12
|
||||
os: windows-latest
|
||||
python: "3.12"
|
||||
cpu_index: true
|
||||
- label: macOS / Python 3.12
|
||||
os: macos-14
|
||||
python: "3.12"
|
||||
cpu_index: false
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
- uses: actions/setup-python@v7
|
||||
with:
|
||||
python-version: ${{ matrix.python }}
|
||||
cache: pip
|
||||
cache-dependency-path: requirements.txt
|
||||
- name: Install CPU PyTorch
|
||||
if: matrix.cpu_index == true
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install torch --index-url https://download.pytorch.org/whl/cpu
|
||||
- name: Install macOS PyTorch
|
||||
if: matrix.cpu_index == false
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install torch
|
||||
- name: Install ComfyUI and node dependencies
|
||||
run: |
|
||||
git clone --depth 1 https://github.com/Comfy-Org/ComfyUI.git ../ComfyUI
|
||||
python -m pip install pytest packaging build
|
||||
python -m pip install -r ../ComfyUI/requirements.txt -r requirements.txt
|
||||
- name: Test
|
||||
run: python -m pytest -q
|
||||
- name: Compile
|
||||
run: python -m compileall -q .
|
||||
- name: Build distribution
|
||||
run: python -m build
|
||||
@@ -0,0 +1,171 @@
|
||||
name: Publish Comfy node fleet
|
||||
|
||||
on:
|
||||
workflow_dispatch:
|
||||
inputs:
|
||||
target:
|
||||
description: Node repository to check
|
||||
required: true
|
||||
default: all
|
||||
type: choice
|
||||
options:
|
||||
- all
|
||||
- vlm
|
||||
- depth
|
||||
- dream
|
||||
- texture
|
||||
schedule:
|
||||
- cron: "17 * * * *"
|
||||
push:
|
||||
branches:
|
||||
- main
|
||||
paths:
|
||||
- ".github/workflows/publish-fleet.yml"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
concurrency:
|
||||
group: comfy-registry-fleet
|
||||
cancel-in-progress: false
|
||||
|
||||
jobs:
|
||||
publish:
|
||||
name: Check ${{ matrix.target }}
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
include:
|
||||
- target: vlm
|
||||
repository: gokayfem/ComfyUI_VLM_nodes
|
||||
node_id: comfyui_vlm_nodes
|
||||
- target: depth
|
||||
repository: gokayfem/ComfyUI-Depth-Visualization
|
||||
node_id: comfyui-depth-visualization
|
||||
- target: dream
|
||||
repository: gokayfem/ComfyUI-Dream-Interpreter
|
||||
node_id: comfyui-dream-interpreter
|
||||
- target: texture
|
||||
repository: gokayfem/ComfyUI-Texture-Simple
|
||||
node_id: comfyui-texture-simple
|
||||
|
||||
steps:
|
||||
- name: Select target
|
||||
id: select
|
||||
env:
|
||||
REQUESTED_TARGET: ${{ inputs.target || 'all' }}
|
||||
MATRIX_TARGET: ${{ matrix.target }}
|
||||
run: |
|
||||
if [[ "$REQUESTED_TARGET" == "all" || "$REQUESTED_TARGET" == "$MATRIX_TARGET" ]]; then
|
||||
echo "selected=true" >> "$GITHUB_OUTPUT"
|
||||
else
|
||||
echo "selected=false" >> "$GITHUB_OUTPUT"
|
||||
fi
|
||||
|
||||
- name: Check out node
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
uses: actions/checkout@v7
|
||||
with:
|
||||
repository: ${{ matrix.repository }}
|
||||
ref: main
|
||||
path: node
|
||||
persist-credentials: false
|
||||
|
||||
- name: Set up Python
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
uses: actions/setup-python@v7
|
||||
with:
|
||||
python-version: "3.12"
|
||||
|
||||
- name: Read and verify release metadata
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
id: metadata
|
||||
working-directory: node
|
||||
env:
|
||||
EXPECTED_NODE_ID: ${{ matrix.node_id }}
|
||||
run: |
|
||||
python - <<'PY'
|
||||
import os
|
||||
import tomllib
|
||||
from pathlib import Path
|
||||
|
||||
metadata = tomllib.loads(Path("pyproject.toml").read_text(encoding="utf-8"))
|
||||
node_id = metadata["project"]["name"]
|
||||
version = metadata["project"]["version"]
|
||||
publisher = metadata["tool"]["comfy"]["PublisherId"]
|
||||
expected = os.environ["EXPECTED_NODE_ID"]
|
||||
|
||||
if node_id != expected:
|
||||
raise SystemExit(f"Expected node id {expected!r}, found {node_id!r}")
|
||||
if publisher != "gokayfem":
|
||||
raise SystemExit(f"Expected publisher 'gokayfem', found {publisher!r}")
|
||||
|
||||
with Path(os.environ["GITHUB_OUTPUT"]).open("a", encoding="utf-8") as output:
|
||||
print(f"node_id={node_id}", file=output)
|
||||
print(f"version={version}", file=output)
|
||||
PY
|
||||
|
||||
- name: Check Registry version
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
id: registry
|
||||
env:
|
||||
NODE_ID: ${{ steps.metadata.outputs.node_id }}
|
||||
VERSION: ${{ steps.metadata.outputs.version }}
|
||||
run: |
|
||||
python - <<'PY'
|
||||
import json
|
||||
import os
|
||||
import urllib.parse
|
||||
import urllib.request
|
||||
from pathlib import Path
|
||||
|
||||
node_id = urllib.parse.quote(os.environ["NODE_ID"], safe="")
|
||||
url = f"https://api.comfy.org/nodes/{node_id}/versions"
|
||||
request = urllib.request.Request(
|
||||
url,
|
||||
headers={"Accept": "application/json", "User-Agent": "comfy-node-fleet-publisher"},
|
||||
)
|
||||
with urllib.request.urlopen(request, timeout=30) as response:
|
||||
versions = json.load(response)
|
||||
|
||||
wanted = os.environ["VERSION"]
|
||||
exists = any(item.get("version") == wanted for item in versions)
|
||||
with Path(os.environ["GITHUB_OUTPUT"]).open("a", encoding="utf-8") as output:
|
||||
print(f"exists={'true' if exists else 'false'}", file=output)
|
||||
PY
|
||||
|
||||
- name: Require publisher credential
|
||||
if: steps.select.outputs.selected == 'true' && steps.registry.outputs.exists != 'true'
|
||||
env:
|
||||
REGISTRY_ACCESS_TOKEN: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
run: |
|
||||
if [[ -z "$REGISTRY_ACCESS_TOKEN" ]]; then
|
||||
echo "::error title=Missing registry token::Add the publisher API key as the REGISTRY_ACCESS_TOKEN repository secret."
|
||||
exit 1
|
||||
fi
|
||||
|
||||
- name: Install pinned publisher
|
||||
if: steps.select.outputs.selected == 'true' && steps.registry.outputs.exists != 'true'
|
||||
run: python -m pip install --disable-pip-version-check --no-input "comfy-cli==1.13.0"
|
||||
|
||||
- name: Publish missing version
|
||||
if: steps.select.outputs.selected == 'true' && steps.registry.outputs.exists != 'true'
|
||||
working-directory: node
|
||||
env:
|
||||
REGISTRY_ACCESS_TOKEN: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
run: comfy --skip-prompt --no-enable-telemetry node publish --token "$REGISTRY_ACCESS_TOKEN"
|
||||
|
||||
- name: Record result
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
env:
|
||||
NODE_ID: ${{ steps.metadata.outputs.node_id }}
|
||||
VERSION: ${{ steps.metadata.outputs.version }}
|
||||
ALREADY_PUBLISHED: ${{ steps.registry.outputs.exists }}
|
||||
run: |
|
||||
if [[ "$ALREADY_PUBLISHED" == "true" ]]; then
|
||||
echo "### $NODE_ID $VERSION already published" >> "$GITHUB_STEP_SUMMARY"
|
||||
else
|
||||
echo "### Published $NODE_ID $VERSION" >> "$GITHUB_STEP_SUMMARY"
|
||||
fi
|
||||
@@ -0,0 +1,114 @@
|
||||
name: Publish to Comfy registry
|
||||
on:
|
||||
workflow_dispatch:
|
||||
push:
|
||||
branches:
|
||||
- main
|
||||
paths:
|
||||
- "pyproject.toml"
|
||||
- ".github/workflows/publish.yml"
|
||||
|
||||
concurrency:
|
||||
group: comfy-registry-${{ github.repository }}
|
||||
cancel-in-progress: false
|
||||
|
||||
env:
|
||||
COMFY_CLI_VERSION: "1.13.0"
|
||||
|
||||
jobs:
|
||||
publish-node:
|
||||
name: Publish Custom Node to registry
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
permissions:
|
||||
contents: read
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@v7
|
||||
with:
|
||||
python-version: "3.12"
|
||||
- name: Read release metadata
|
||||
id: metadata
|
||||
run: |
|
||||
python - <<'PY'
|
||||
import os
|
||||
import tomllib
|
||||
from pathlib import Path
|
||||
|
||||
metadata = tomllib.loads(Path("pyproject.toml").read_text(encoding="utf-8"))
|
||||
node_id = metadata["project"]["name"]
|
||||
version = metadata["project"]["version"]
|
||||
publisher = metadata["tool"]["comfy"]["PublisherId"]
|
||||
if publisher != "gokayfem":
|
||||
raise SystemExit(f"Expected publisher 'gokayfem', found {publisher!r}")
|
||||
|
||||
with Path(os.environ["GITHUB_OUTPUT"]).open("a", encoding="utf-8") as output:
|
||||
print(f"node_id={node_id}", file=output)
|
||||
print(f"version={version}", file=output)
|
||||
PY
|
||||
- name: Check Registry version
|
||||
id: registry
|
||||
env:
|
||||
NODE_ID: ${{ steps.metadata.outputs.node_id }}
|
||||
VERSION: ${{ steps.metadata.outputs.version }}
|
||||
run: |
|
||||
python - <<'PY'
|
||||
import json
|
||||
import os
|
||||
import urllib.parse
|
||||
import urllib.request
|
||||
from pathlib import Path
|
||||
|
||||
node_id = urllib.parse.quote(os.environ["NODE_ID"], safe="")
|
||||
request = urllib.request.Request(
|
||||
f"https://api.comfy.org/nodes/{node_id}/versions",
|
||||
headers={"Accept": "application/json", "User-Agent": "comfy-node-publisher"},
|
||||
)
|
||||
with urllib.request.urlopen(request, timeout=30) as response:
|
||||
versions = json.load(response)
|
||||
|
||||
exists = any(item.get("version") == os.environ["VERSION"] for item in versions)
|
||||
with Path(os.environ["GITHUB_OUTPUT"]).open("a", encoding="utf-8") as output:
|
||||
print(f"exists={'true' if exists else 'false'}", file=output)
|
||||
PY
|
||||
- name: Check publisher credential
|
||||
if: steps.registry.outputs.exists != 'true'
|
||||
id: credentials
|
||||
env:
|
||||
REGISTRY_ACCESS_TOKEN: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
run: |
|
||||
if [[ -n "$REGISTRY_ACCESS_TOKEN" ]]; then
|
||||
echo "available=true" >> "$GITHUB_OUTPUT"
|
||||
else
|
||||
echo "available=false" >> "$GITHUB_OUTPUT"
|
||||
echo "::notice title=Central publisher enabled::The secure fleet publisher will publish this release within one hour."
|
||||
fi
|
||||
- name: Install pinned Comfy CLI
|
||||
if: steps.registry.outputs.exists != 'true' && steps.credentials.outputs.available == 'true'
|
||||
shell: bash
|
||||
run: python -m pip install --disable-pip-version-check "comfy-cli==${COMFY_CLI_VERSION}"
|
||||
- name: Publish Custom Node
|
||||
if: steps.registry.outputs.exists != 'true' && steps.credentials.outputs.available == 'true'
|
||||
id: publish
|
||||
continue-on-error: true
|
||||
shell: bash
|
||||
env:
|
||||
REGISTRY_ACCESS_TOKEN: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
run: comfy --skip-prompt --no-enable-telemetry node publish --token "$REGISTRY_ACCESS_TOKEN"
|
||||
- name: Record publication result
|
||||
env:
|
||||
NODE_ID: ${{ steps.metadata.outputs.node_id }}
|
||||
VERSION: ${{ steps.metadata.outputs.version }}
|
||||
ALREADY_PUBLISHED: ${{ steps.registry.outputs.exists }}
|
||||
PUBLISH_OUTCOME: ${{ steps.publish.outcome }}
|
||||
run: |
|
||||
if [[ "$ALREADY_PUBLISHED" == "true" ]]; then
|
||||
echo "### $NODE_ID $VERSION already published" >> "$GITHUB_STEP_SUMMARY"
|
||||
elif [[ "$PUBLISH_OUTCOME" == "success" ]]; then
|
||||
echo "### Published $NODE_ID $VERSION" >> "$GITHUB_STEP_SUMMARY"
|
||||
else
|
||||
echo "::notice title=Central publishing handoff::The secure fleet publisher will retry this release within one hour."
|
||||
echo "### $NODE_ID $VERSION queued for the fleet publisher" >> "$GITHUB_STEP_SUMMARY"
|
||||
fi
|
||||
@@ -0,0 +1,261 @@
|
||||
# Platform and accelerator compatibility
|
||||
|
||||
ComfyUI owns PyTorch. This node pack deliberately does not depend on `torch`,
|
||||
`torchvision`, or a vendor wheel, because installing a generic PyPI build can
|
||||
silently replace a working CUDA, ROCm, XPU, or Metal environment.
|
||||
|
||||
Install `requirements.txt` with the same Python executable that starts ComfyUI.
|
||||
The **VLM Runtime Diagnostics** node reports the environment seen by the pack
|
||||
without downloading a model.
|
||||
|
||||
## Support matrix
|
||||
|
||||
| Platform | Managed Transformers | bitsandbytes 4/8-bit | GGUF acceleration |
|
||||
| --- | --- | --- | --- |
|
||||
| Linux + NVIDIA | CUDA, BF16/FP16 capability detected | Official wheel | CUDA or Vulkan |
|
||||
| Windows + NVIDIA | CUDA, BF16/FP16 capability detected | Official wheel | CUDA or Vulkan |
|
||||
| Linux + AMD | ROCm through PyTorch's `cuda` API | Official ROCm wheel for listed GPU architectures | ROCm/HIP or Vulkan |
|
||||
| Windows + AMD | Current ComfyUI/AMD ROCm PyTorch builds | Official ROCm Windows wheel for listed GPU architectures | HIP Radeon or Vulkan |
|
||||
| Apple Silicon macOS | MPS, BF16 on supported macOS/PyTorch; FP16 fallback | Official arm64 wheel | Metal |
|
||||
| Intel GPU | XPU with BF16 capability detection | Official XPU/CPU wheel | SYCL or Vulkan |
|
||||
| CPU | FP32 | Official wheels on supported architectures | OpenBLAS or default CPU |
|
||||
| Intel macOS | CPU/legacy MPS environment as provided by ComfyUI | No official bitsandbytes wheel; dependency is skipped | CPU build |
|
||||
|
||||
The default **ComfyUI managed** mode is the portable path. Quantization is an
|
||||
optional optimization, not an import requirement. DirectML/private-use devices
|
||||
receive a safe FP32 fallback, but are best-effort because current ComfyUI itself
|
||||
does not treat DirectML as a primary performance backend.
|
||||
|
||||
## Detection and segmentation backends
|
||||
|
||||
The structured vision nodes do not install a second PyTorch build. Grounding
|
||||
DINO, OWLv2, OmDet Turbo, Florence-2, and SAM2.1 use the device selected by
|
||||
ComfyUI and participate in its model loading/offloading lifecycle. The core
|
||||
SAM3.1 adapter performs schema validation and report generation on the compact
|
||||
core payload; ComfyUI itself owns SAM3 inference and mask packing.
|
||||
|
||||
| Backend | Detection / Florence | SAM2.1 video | Comfy core SAM3.1 | Practical limitation |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| NVIDIA CUDA | Managed BF16 when supported, otherwise FP16 | Preferred accelerated path; CPU state/storage is the default | Supported when the installed ComfyUI version recognizes the checkpoint | Resolution, frame count, and object count still dominate VRAM/RAM |
|
||||
| AMD ROCm on Linux | Uses PyTorch's `cuda` device and BF16/FP16 capability checks | Same managed path; keep inference state on CPU unless measured otherwise | Follows ComfyUI core ROCm support | Individual Transformers kernels may fall back or differ in performance |
|
||||
| AMD ROCm on Windows | Uses the device exposed by the selected ComfyUI PyTorch build | Same API contract | Follows that ComfyUI build | Treat as hardware-validation pending, not equivalent to a Linux ROCm pass |
|
||||
| Apple Metal / MPS | FP16, or BF16 only when macOS/PyTorch report support | Supported contract with CPU video storage; use Tiny and short slices first | Follows ComfyUI core MPS support | Unified memory is shared with the OS; unsupported operators may fall back to CPU |
|
||||
| Intel XPU | BF16/FP16 capability-selected managed path | Supported contract; use CPU state for portability | Follows ComfyUI core XPU support | Model-specific operator coverage and real throughput require hardware validation |
|
||||
| CPU | FP32 portable path | Functionally supported but slow; use Tiny, low resolution, and short slices | Adapter/report works; core SAM3 inference is memory intensive | No half-precision speed assumption and no accelerator kernel |
|
||||
|
||||
`precision=auto` is the safe default for open-vocabulary detection and SAM2.1.
|
||||
Explicit BF16 silently falls back to FP16 or FP32 when the selected backend
|
||||
cannot execute BF16. This is a portability fallback, not proof that every
|
||||
model family has been run on every vendor device. See
|
||||
[MODEL_VALIDATION.md](MODEL_VALIDATION.md) for real-hardware evidence.
|
||||
|
||||
### Moondream 3 / 3.1 Photon
|
||||
|
||||
Moondream Photon is deliberately isolated from ComfyUI's main Python environment
|
||||
because `moondream==1.3.0` requires Pillow 10 while current ComfyUI uses a
|
||||
newer Pillow. Its worker cache, virtual environment, and logs live under
|
||||
`models/LLavacheckpoints/moondream31-runtime`; it never replaces ComfyUI's
|
||||
PyTorch or Pillow.
|
||||
|
||||
| Platform | Official local Photon support | This integration |
|
||||
| --- | --- | --- |
|
||||
| Linux/WSL + NVIDIA Ampere or newer | Supported | 3.1 query/caption/detection/pointing; 3 Preview SVG segmentation |
|
||||
| Windows + NVIDIA Ampere or newer | Supported | Same isolated worker contract |
|
||||
| Apple Silicon macOS 13+ | Supported with MPS | Same contract; use a conservative KV-cache profile on low-memory systems |
|
||||
| AMD ROCm, Intel GPU, CPU | Not currently provided upstream | Node stays importable and fails before model work with an actionable support message |
|
||||
|
||||
The final Moondream 3.1 model card lists query, caption, detect, and point; it
|
||||
does not list segment. Native SVG segment uses `moondream3-preview`, and the
|
||||
loader rejects a 3.1/segment mismatch before inference.
|
||||
|
||||
`max_batch_size` controls Photon's scheduler capacity. The detection, point,
|
||||
and preview-segmentation nodes issue `parallel_requests` frame requests concurrently,
|
||||
allowing Photon to build GPU batches. `frame_stride` bounds work for high-frame
|
||||
rate sources. Performance JSON records warm worker time, end-to-end time,
|
||||
processed/skipped frames, worker/sustained FPS, target sampled FPS, and
|
||||
real-time factor; it is a measurement from the current run, not a universal
|
||||
benchmark claim.
|
||||
|
||||
### Video memory and chunking
|
||||
|
||||
- Core `Video Slice` should bound work before `GetVideoComponents` materializes
|
||||
frames. Scale the resulting `IMAGE` batch before running detection or
|
||||
segmentation.
|
||||
- Open-vocabulary detection runs frame by frame. SAM2.1 keeps source frames on
|
||||
CPU, defaults its inference state to CPU, and caches at most one vision
|
||||
feature in the video session.
|
||||
- SAM2.1 output masks and previews are CPU tensors. Core SAM3 keeps its track
|
||||
masks bit-packed; `VLMSAM3TrackAdapter` does not unpack the complete volume.
|
||||
- `unload_after=true` releases the node's owned detector/SAM2 model after a
|
||||
run. Leave it false for repeated work with one model; set it true before a
|
||||
different large family must load on a constrained accelerator.
|
||||
- Each slice or queue run starts a new propagation/tracking session. Carrying
|
||||
an ID across independent chunks requires an explicit application-level
|
||||
overlap/reconciliation step; the nodes never claim cross-run identity.
|
||||
|
||||
### Model licenses and access
|
||||
|
||||
Model licenses are independent from this repository's code license. Check the
|
||||
model card before redistributing weights or outputs.
|
||||
|
||||
- The `facebook/sam2.1-hiera-*` Transformers checkpoints are published under
|
||||
Apache-2.0.
|
||||
- Meta SAM3 uses the SAM License. The upstream `facebook/sam3` repository is
|
||||
access-gated and asks the Hugging Face account holder to accept its terms and
|
||||
share the requested contact information.
|
||||
- ComfyUI's `Comfy-Org/sam3.1` checkpoint is marked `sam-license`; the example
|
||||
expects `sam3.1_multiplex_fp16.safetensors` under
|
||||
`ComfyUI/models/checkpoints`.
|
||||
- `HF_TOKEN` is used when Hugging Face requires authenticated access. Tokens
|
||||
must be supplied by the environment and must not be embedded in workflows.
|
||||
- Moondream 3.1 uses the Moondream Model License 1.0. The Loader requires an
|
||||
explicit workflow acknowledgement. The license permits local product use
|
||||
but restricts offering general-purpose hosted Moondream access; review the
|
||||
current upstream terms for the intended deployment.
|
||||
|
||||
Authoritative references:
|
||||
|
||||
- [Meta SAM3 model and access terms](https://huggingface.co/facebook/sam3)
|
||||
- [Meta SAM3 license](https://huggingface.co/facebook/sam3/blob/main/LICENSE)
|
||||
- [ComfyUI SAM3.1 checkpoint](https://huggingface.co/Comfy-Org/sam3.1)
|
||||
- [SAM2.1 Hiera Tiny model card](https://huggingface.co/facebook/sam2.1-hiera-tiny)
|
||||
- [Moondream 3.1 model card](https://huggingface.co/moondream/moondream3.1-9B-A2B)
|
||||
- [Moondream Model License 1.0](https://moondream.ai/licenses/model/1.0)
|
||||
|
||||
## Dependency behavior
|
||||
|
||||
- Python 3.10 through 3.13 is covered by CI.
|
||||
- `transformers>=5.4,<6` and `huggingface-hub>=1.5,<2` are paired intentionally;
|
||||
Transformers 5.4 requires Hub 1.5 or newer.
|
||||
- `bitsandbytes>=0.50` is the first dependency floor used here for the current
|
||||
multi-backend releases. Environment markers prevent an unsupported wheel
|
||||
from blocking the whole node pack.
|
||||
- `requirements-quantization.txt` is available for an explicit quantization
|
||||
install or source-build environment.
|
||||
- `requirements-moondream31.txt` belongs only in the isolated Photon sidecar;
|
||||
installing it into ComfyUI's environment would create a Pillow conflict.
|
||||
- Model downloads, imports, and package compilation never occur during node
|
||||
discovery.
|
||||
|
||||
Install manually:
|
||||
|
||||
```bash
|
||||
python -m pip install -r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements.txt
|
||||
```
|
||||
|
||||
If quantization was skipped but the machine has a supported custom build:
|
||||
|
||||
```bash
|
||||
python -m pip install -r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements-quantization.txt
|
||||
```
|
||||
|
||||
## llama.cpp / GGUF
|
||||
|
||||
`llama-cpp-python` must be compiled or selected for the actual backend. Its
|
||||
official project currently publishes backend indexes and documents source
|
||||
build flags:
|
||||
|
||||
```bash
|
||||
# NVIDIA; choose a wheel supported by the installed driver.
|
||||
python -m pip install llama-cpp-python \
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/cu124
|
||||
|
||||
# Apple Metal
|
||||
python -m pip install llama-cpp-python \
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/metal
|
||||
|
||||
# Linux ROCm
|
||||
python -m pip install llama-cpp-python \
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/rocm72
|
||||
|
||||
# Linux or Windows Vulkan
|
||||
python -m pip install llama-cpp-python \
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/vulkan
|
||||
```
|
||||
|
||||
If an Apple Metal wheel is unavailable or fails archive validation, build the
|
||||
same optional requirement from source:
|
||||
|
||||
```bash
|
||||
CMAKE_ARGS="-DGGML_METAL=on" python -m pip install \
|
||||
--no-cache-dir --no-binary llama-cpp-python \
|
||||
-r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements-llama-cpp.txt
|
||||
```
|
||||
|
||||
The official Windows HIP Radeon index is:
|
||||
|
||||
```powershell
|
||||
python -m pip install llama-cpp-python `
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/hip-radeon
|
||||
```
|
||||
|
||||
Source builds use `GGML_CUDA=on`, `GGML_METAL=on`, `GGML_HIP=on`,
|
||||
`GGML_VULKAN=on`, or `GGML_SYCL=on` through `CMAKE_ARGS`. Use an arm64 Python
|
||||
on Apple Silicon; an x86 Python builds the wrong architecture and is
|
||||
dramatically slower.
|
||||
|
||||
The llama.cpp wheel is an independent native runtime; it does not have to use
|
||||
the same accelerator API as ComfyUI's PyTorch wheel. For example, a Vulkan
|
||||
llama.cpp wheel can coexist with a CUDA or CPU PyTorch build. The nodes query
|
||||
`llama_supports_gpu_offload`, `llama_supports_mmap`, and llama.cpp's system
|
||||
information at runtime. They never label a wheel CUDA/ROCm/Metal based only on
|
||||
`torch`.
|
||||
|
||||
### GGUF runtime controls
|
||||
|
||||
- `gpu_layers=-1` requests full accelerator offload. A build that reports no
|
||||
offload support is automatically clamped to `0` and continues on CPU.
|
||||
- `n_batch` is the logical prompt batch and `n_ubatch` is the physical
|
||||
micro-batch. The runtime clamps both to the selected context and guarantees
|
||||
`n_ubatch <= n_batch`.
|
||||
- **Auto** flash attention enables the optimized path for accelerator offload
|
||||
and retries once without it only when llama.cpp reports an attention-related
|
||||
initialization failure. **Enabled** remains strict; **Disabled** is the
|
||||
maximum-compatibility setting.
|
||||
- `use_mmap` is honored only when the compiled backend reports mmap support.
|
||||
- Layer, row, and single-device split modes plus `main_gpu` and
|
||||
comma-separated `tensor_split` weights are passed through when supported by
|
||||
the installed binding. Parallel multi-GPU is primarily a CUDA/ROCm feature;
|
||||
Vulkan and SYCL support is more limited.
|
||||
- Current multimodal GGUFs should use **Auto (GGUF chat template)**, which maps
|
||||
to llama.cpp's MTMD handler. Named legacy handlers remain selectable for
|
||||
model cards that require an exact prompt format.
|
||||
- Every model handle is lazy, mutex-protected, cache-keyed by all performance
|
||||
settings, and closes its exact model and projector handler on unload.
|
||||
|
||||
Authoritative installation references:
|
||||
|
||||
- [ComfyUI installation and hardware backends](https://github.com/Comfy-Org/ComfyUI)
|
||||
- [bitsandbytes installation and supported hardware](https://huggingface.co/docs/bitsandbytes/installation)
|
||||
- [llama-cpp-python supported backends](https://github.com/abetlen/llama-cpp-python#supported-backends)
|
||||
- [llama-cpp-python API reference](https://llama-cpp-python.readthedocs.io/en/latest/api-reference/)
|
||||
- [llama.cpp backend feature matrix](https://github.com/ggml-org/llama.cpp/wiki/Feature-matrix)
|
||||
|
||||
## Attention and offloading
|
||||
|
||||
- **Auto (SDPA)** lets PyTorch choose its maintained kernel and is the default
|
||||
on every backend.
|
||||
- **Flash Attention 2** is preflighted for CUDA/ROCm only. A compatible
|
||||
`flash-attn` build is still required.
|
||||
- ComfyUI-managed models participate in its normal model patcher lifecycle.
|
||||
- External bitsandbytes and llama.cpp allocations ask ComfyUI to free space
|
||||
first, then release only their owned model on unload.
|
||||
- Automatic CPU/disk device mapping is used for large CUDA/ROCm/XPU models.
|
||||
MPS unified memory and CPU use an explicit active-device map.
|
||||
- AudioLDM2 uses FP16 on capable accelerators, FP32 on CPU, CUDA-API CPU
|
||||
offload for NVIDIA/ROCm, and a portable CPU random generator on MPS.
|
||||
|
||||
## What CI proves
|
||||
|
||||
Every push installs current ComfyUI plus this complete `requirements.txt` and
|
||||
runs imports, schemas, runtime contracts, tests, and byte-compilation on:
|
||||
|
||||
- Ubuntu, Python 3.10
|
||||
- Ubuntu, Python 3.13
|
||||
- Windows, Python 3.12
|
||||
- macOS, Python 3.12
|
||||
|
||||
Hosted runners do not contain production NVIDIA, AMD, or Intel GPUs. CI
|
||||
therefore tests backend selection and dtype/device-map contracts, while real
|
||||
GPU model smoke tests remain explicit hardware validation. It does not claim
|
||||
that a CPU simulation executed a vendor kernel.
|
||||
@@ -0,0 +1,121 @@
|
||||
# Model validation
|
||||
|
||||
Validated on 2026-07-29 with ComfyUI 0.28.0, Python 3.12, Transformers 5.14.1,
|
||||
PyTorch 2.13.0+cu126, and an RTX 3090 24 GB. All models and caches were stored
|
||||
on the D drive and executed through WSL.
|
||||
|
||||
## Real-weight passes
|
||||
|
||||
| Family | Representative result | Peak CUDA |
|
||||
| --- | --- | ---: |
|
||||
| Qwen 3.5 | 0.8B BF16 image/video; 0.8B NF4; 2B, 4B, and 9B images | 0.82–17.62 GiB |
|
||||
| Qwen 3 VL | 2B, 4B, and 8B images returned the correct red object | 3.99–16.37 GiB |
|
||||
| SmolVLM2 | 500M image/video and 2.2B video returned the correct object | 2.29–5.41 GiB |
|
||||
| LFM2.5 VL | 450M returned “red … rectangle” | 0.88 GiB |
|
||||
| InternVL 3.5 | 1B video returned “green rectangle” after the 448px patch-grid fix | 2.14 GiB |
|
||||
| Granite Vision 4.1 | 4B returned “solid red square” through native Transformers code | 7.61 GiB |
|
||||
| Florence-2 | Native converted base-FT returned and parsed a bright-red-square caption | 0.59 GiB |
|
||||
| llama.cpp GGUF | Official Qwen3.5-0.8B Q4_0 with llama-cpp-python 0.3.34 CUDA loaded in 20.015s and generated the exact requested response in 0.654s | < 1 GiB model weights |
|
||||
|
||||
One checkpoint covers sibling sizes that use the same architecture and loader.
|
||||
The node does not download every size simply to repeat the same integration
|
||||
test.
|
||||
|
||||
## ComfyUI API pass
|
||||
|
||||
ComfyUI started from the D-drive WSL installation with all four repaired custom
|
||||
node repositories enabled and no custom-node import failures. A real local API
|
||||
workflow (`EmptyImage` -> `ModernVLM` -> `ViewText`) ran the cached LFM2.5-VL
|
||||
450M checkpoint on a solid red input, returned `Red.`, and completed with
|
||||
`unload_after=true`. Prompt ID:
|
||||
`919f92cd-ecb2-487b-abf0-19f5e4d88229`.
|
||||
|
||||
A second real local API workflow (`LLMLoader` -> `LLMSampler` -> `ViewText`)
|
||||
used the official 563 MB `ggml-org/Qwen3.5-0.8B-GGUF` Q4_0 checkpoint with
|
||||
full GPU offload, `n_batch=256`, `n_ubatch=128`, mmap, and Auto flash
|
||||
attention. It returned exactly `ComfyUI llama API ready` and completed
|
||||
successfully. Prompt ID: `eed8458d-de7f-47ac-8ebf-e48e4dacc2d6`.
|
||||
|
||||
The installed llama.cpp CUDA 12.4 wheel reported GPU offload, mmap, and mlock
|
||||
support directly. CPU-only fallback, Metal/Vulkan/SYCL/ROCm-independent
|
||||
capability detection, multi-GPU options, and flash-attention retry are covered
|
||||
by simulated backend contract tests; those vendor kernels were not claimed as
|
||||
real hardware passes on the NVIDIA test machine.
|
||||
|
||||
## Catalog validation
|
||||
|
||||
Configuration and processor resolution passed for all 15 ungated entries in
|
||||
the small/fast catalog: Qwen 3.5 0.8B/2B/4B, Qwen 3 VL 2B/4B, Qwen 2.5 VL 3B,
|
||||
SmolVLM2 256M/500M/2.2B, LFM2.5 VL 450M/1.6B, InternVL 3.5 1B/2B, and Granite
|
||||
Vision 3.3 2B/4.1 4B. Gemma 3 4B is the sixteenth entry and correctly requires
|
||||
license acceptance plus `HF_TOKEN`.
|
||||
|
||||
## Structured vision validation
|
||||
|
||||
The versioned detection/track/point/event payloads, geometry and mask
|
||||
conversion, strict spatial parser, Grounding-family adapters, SAM2.1 session
|
||||
plumbing, SAM3 bit-packed payload adapter, and ByteTrack-style association pass
|
||||
the local WSL contract suite. Those tests validate schemas, shapes, output
|
||||
ordering, bounds, timestamps, deterministic IDs, and error handling.
|
||||
|
||||
Representative real-weight checks were then submitted through ComfyUI's local
|
||||
`POST /prompt` API and verified from `/history/{prompt_id}`. The test machine
|
||||
used ComfyUI 0.28.0, Python 3.12.12, PyTorch 2.13.0+cu126, Transformers 5.14.1,
|
||||
and an NVIDIA RTX 3090. Input media, checkpoints, model caches, ComfyUI, and
|
||||
this checkout all remained on the D drive under WSL.
|
||||
|
||||
| Family | Representative checkpoint policy | Real-weight status |
|
||||
| --- | --- | --- |
|
||||
| Grounding DINO | Tiny; Base uses the same loader/processor contract | **Passed**: FP16, four real 640x360 video frames in two-frame micro-batches; person and bird boxes/labels were visually checked, serialized, timestamped, and in bounds |
|
||||
| OWLv2 | Base Ensemble | Pending |
|
||||
| OmDet Turbo | Swin Tiny | Pending |
|
||||
| SAM2.1 video | Hiera Tiny; sibling sizes use the same session adapter | **Passed**: FP16, real 12-frame 640x360 clip at 24 FPS with CPU preprocessing/state. Grounding's core `BOUNDING_BOX` output connected directly: the forward union-only run kept one person ID on frames 0-11; a last-frame reverse run kept two IDs for 24 observations and emitted 24 frame-major object masks. All geometry was in bounds and first/last overlays and masks were visually checked |
|
||||
| Comfy core SAM3.1 | `sam3.1_multiplex_fp16.safetensors`, only after license/access is available | Pending |
|
||||
| SAM3 adapter/report | Synthetic core payload contract | Passed without weights; real core handoff pending |
|
||||
| ByteTrack-style tracker | Deterministic synthetic crossing, missed-frame, and expiry cases | Passed; no model weights exist |
|
||||
| Florence-2 multitask | Base FT; Large uses the same native Transformers contract | **Passed**: real object-detection API run produced bounded woman, face, and clothing boxes plus a visually checked overlay |
|
||||
|
||||
The SAM2 API check initially exposed a real session-lifecycle defect that unit
|
||||
fixtures did not: prompt insertion must be followed by inference on the seeded
|
||||
frame before propagation. The implementation now performs that seed pass and
|
||||
also propagates in reverse when `seed_frame` is greater than zero. Later live
|
||||
checks exercised nested multi-object core boxes, CPU preprocessing/state,
|
||||
union-only low-memory output, optional object-mask output, disabled preview
|
||||
rendering, reverse propagation, and `unload_after=true` for both models. The
|
||||
final unload run returned total reported GPU memory use to within 4 MiB of the
|
||||
pre-run `nvidia-smi` baseline.
|
||||
|
||||
Grounding DINO and SAM2 sibling sizes are catalog-available but were not
|
||||
downloaded or executed. OWLv2, OmDet Turbo, and gated SAM3 remain explicitly
|
||||
unverified; the UI never presents them as locally tested simply because their
|
||||
schemas import.
|
||||
|
||||
The acceptance run for each model family must record:
|
||||
|
||||
1. Exact checkpoint revision, ComfyUI/Python/PyTorch/Transformers versions,
|
||||
device, dtype, peak accelerator allocation, and wall time.
|
||||
2. A real image or short bounded video with manually verified boxes, labels,
|
||||
masks, timestamps, and stable IDs.
|
||||
3. The canonical JSON schema/version and every advertised output socket,
|
||||
including preview/report output through ComfyUI's local `/prompt` API.
|
||||
4. A second queue using the cached model, followed by an `unload_after=true`
|
||||
run where that option exists.
|
||||
5. Failure behavior for an absent checkpoint or gated access without exposing
|
||||
a token.
|
||||
|
||||
One checkpoint per distinct implementation family is enough for sibling model
|
||||
sizes that share the same code path. Validation prioritizes the smallest useful
|
||||
checkpoint and will not download or execute a 30B model. A larger variant is
|
||||
tested only when it has a different loader, processor, postprocessor, or
|
||||
quantization path.
|
||||
|
||||
## Not marked passed
|
||||
|
||||
- Qwen 3 VL 30B-A3B: weights are available locally, but inference validation
|
||||
was stopped at the user's request and will not be repeated.
|
||||
- Moondream2 2025-06-21: its pinned remote wrapper needed Transformers 5 loading
|
||||
metadata, but this Torch/CUDA stack produced NaN probabilities when sampling
|
||||
and immediate EOS with greedy decoding. The node defaults to the
|
||||
non-destructive greedy path and raises an actionable error on an empty result.
|
||||
- PaLI-Gemma and Gemma 3: gated checkpoints were not accessible without an
|
||||
accepted license and token.
|
||||
@@ -1,94 +1,606 @@
|
||||
<div align="center">
|
||||
<h1> 👁️ VLM Nodes</h1>
|
||||
<p align="center">
|
||||
<b> 🔽Examples below</b> •
|
||||
📙 <a href="https://github.com/gokayfem/Awesome-VLM-Architectures">Visit my other repo to learn more about Vision Language Models</a>
|
||||
</p>
|
||||
</div>
|
||||
<br/>
|
||||
# ComfyUI VLM Nodes
|
||||
|
||||
## Usage
|
||||
Production-oriented vision-language, structured prompting, audio, and utility
|
||||
nodes for ComfyUI. Version 3.3 supports ComfyUI's selected NVIDIA CUDA, AMD
|
||||
ROCm, Apple Metal, Intel XPU, and CPU device without replacing its PyTorch
|
||||
build. It removes startup installers and global accelerator cache flushes,
|
||||
adds real image/video batches and live token streaming, and uses ComfyUI model
|
||||
residency and offloading.
|
||||
|
||||
## Modern model coverage
|
||||
|
||||
The **Modern VLM** node provides one stable interface with a deliberately
|
||||
small, 12-choice production picker:
|
||||
|
||||
- Qwen 3.5 0.8B and 4B
|
||||
- Qwen 3 VL 2B, 4B, and 8B Instruct
|
||||
- SmolVLM2 500M and 2.2B Video
|
||||
- Liquid LFM2.5-VL 450M
|
||||
- InternVL 3.5 1B
|
||||
- Granite Vision 4.1 4B
|
||||
- Gemma 3 4B IT
|
||||
- a compatible custom Hugging Face image-to-text repository
|
||||
|
||||
The separate **[Legacy] Modern VLM Compatibility** node contains redundant,
|
||||
superseded, experimental, and very large tiers:
|
||||
|
||||
- Qwen 3.5 2B, 9B, 27B, and 35B-A3B
|
||||
- Qwen 3.6 27B
|
||||
- Qwen 3 VL 30B-A3B Instruct
|
||||
- Qwen 2.5 VL 3B and 7B for existing workflows
|
||||
- Gemma 3 12B and 27B IT
|
||||
- SmolVLM2 256M Video
|
||||
- Liquid LFM2.5-VL 1.6B
|
||||
- InternVL 3.5 2B
|
||||
- Granite Vision 3.3 2B
|
||||
|
||||
Previously saved `ModernVLM` workflows remain valid even when their selected
|
||||
model moved to Legacy. The server accepts every known catalog value for
|
||||
backward compatibility; only the visible new-workflow picker is curated.
|
||||
Dedicated Molmo, PaLI-Gemma, Qwen2-VL, MiniCPM-V, Kosmos-2, MC-LLaVA, UForm,
|
||||
and script-style MoonDream nodes are also collected under
|
||||
`VLM Nodes/Legacy/Model Loaders`. Maintained creator-facing Florence-2,
|
||||
Moondream2, JoyTag, llama.cpp/GGUF, detection, segmentation, tracking, API,
|
||||
and video-intelligence nodes stay in their functional categories.
|
||||
|
||||
Sixteen curated sub-4B/low-VRAM choices are marked internally as the
|
||||
small-and-fast tier. The default is Qwen 3 VL 2B: it is much quicker to load
|
||||
than larger checkpoints while retaining broad image and video understanding.
|
||||
The catalog intentionally uses official model repositories and maintained
|
||||
Transformers interfaces rather than unverified community quantizations.
|
||||
Curated models use native Transformers implementations; remote repository code
|
||||
is enabled only when the explicit custom-model option requires it. Florence-2
|
||||
uses the Transformers-native converted checkpoints instead of Microsoft’s
|
||||
legacy repository code.
|
||||
|
||||
## Live text output
|
||||
|
||||
`Modern VLM` streams decoded text through ComfyUI's native `progress_text`
|
||||
WebSocket channel by default. A connected `ViewText` node updates while tokens
|
||||
arrive, shows the final response after execution, and restores the last result
|
||||
when ComfyUI rehydrates workflow output history. Disable `stream_output` for
|
||||
API-only or headless runs that do not need incremental UI updates. Streaming is
|
||||
best-effort and never changes the final `STRING` output or makes inference fail.
|
||||
|
||||
## Text workflow toolkit
|
||||
|
||||
The original `SimpleText`, `JsonToText`, and `ViewText` node IDs and their
|
||||
first `STRING` outputs remain stable for saved workflows. They now live in
|
||||
organized `VLM Nodes/Text` subcategories and expose descriptive names, search
|
||||
aliases, tooltips, appended metrics, and strict error messages:
|
||||
|
||||
| Node | Purpose |
|
||||
| --- | --- |
|
||||
| `Text` (`SimpleText`) | Multiline/dynamic prompt source with optional edge/newline normalization and character, word, and line outputs |
|
||||
| `View Text (Streaming)` | Read-only live output with counts, copy, UTF-8 download, line wrapping, stream following, reroute traversal, and history rehydration |
|
||||
| `JSON to Text` | Plain or fenced JSON parsing with readable, values-only, key/value, pretty, and compact render modes |
|
||||
| `Text Join` | Join up to eight prompt/context values with empty-value removal and stable deduplication |
|
||||
| `Text Template` | Safe named placeholders from a JSON object plus four convenient live text sockets, with explicit missing-key policy |
|
||||
| `Text Clean` | Unicode NFC/NFKC, newline/whitespace cleanup, enclosing Markdown-fence removal, line deduplication, and deterministic length caps |
|
||||
| `Text Replace` | Literal or regex substitution with case, count, and missing-pattern controls |
|
||||
| `JSON Extract` | JSONPath-lite (`$.items[0]`) and RFC 6901 JSON Pointer extraction from plain or fenced model responses |
|
||||
| `Text Split / Batch` | Lines, paragraphs, delimiters, regex, CSV, or JSON arrays converted to a real mapped Comfy `STRING` list |
|
||||
| `Text Inspector` | Pass-through text plus characters, UTF-8 bytes, words, lines, rough token budget, SHA-256, and JSON metadata |
|
||||
|
||||
The JSON utilities never evaluate code, follow references, access files, or
|
||||
make network requests. Template fields are direct names rather than Python
|
||||
attribute/index expressions. `approx_tokens` is deliberately labeled as a
|
||||
rough UTF-8 budget estimate; use the target model tokenizer when exact billing
|
||||
or context accounting matters.
|
||||
|
||||
Specialized nodes remain available where a generic chat node would discard
|
||||
useful model capabilities:
|
||||
|
||||
- **Moondream 3.1 9B-A2B**: official 2B-active Photon runtime with query,
|
||||
caption, and high-throughput image/video detection and pointing.
|
||||
- **Moondream 3 Preview segment**: native SVG segmentation through the same
|
||||
isolated Photon loader. The SVG is preserved and also converted into antialiased
|
||||
`MASK`, black/white previews, foreground cutouts, overlays, polygons,
|
||||
canonical `VLM_DETECTIONS`, and core bounding boxes. Detection/pointing
|
||||
submit frames concurrently so Photon can dynamically batch them; every run
|
||||
reports measured worker FPS, end-to-end FPS, and real-time factor.
|
||||
- **Florence-2**: captioning, OCR, detection, region captioning, and referring
|
||||
expression segmentation, with structured JSON, mask, and overlay outputs.
|
||||
- **PaLI-Gemma**: caption/VQA plus the official 16-token VQ-VAE segmentation
|
||||
decoder; segmentation tokens are no longer misinterpreted as polygon points.
|
||||
- **Moondream2**: pinned query API with explicit decoding controls. The official
|
||||
checkpoint is loaded through its native safetensors state dict, avoiding the
|
||||
silent empty-output regression in Transformers 5 while retaining ComfyUI
|
||||
managed loading and unloading.
|
||||
- **Qwen2-VL**: image batches and real video-frame batches.
|
||||
- **Legacy Molmo, Kosmos-2, UForm, MCLLaVA, and MiniCPM-V 2.6 GGUF**, plus
|
||||
maintained JoyTag.
|
||||
- **llama.cpp LLaVA/GGUF**, structured prompt suggestions, OpenAI-compatible
|
||||
prompting, and AudioLDM2.
|
||||
|
||||
## Structured detection, segmentation, and tracking
|
||||
|
||||
The vision nodes use stable, typed sockets instead of passing model-specific
|
||||
lists between nodes:
|
||||
|
||||
| Socket | JSON schema | Purpose |
|
||||
| --- | --- | --- |
|
||||
| `VLM_DETECTIONS` | `comfyui-vlm/detections`, version 1 | Per-frame boxes, labels, scores, optional polygons/quads, and in-process masks |
|
||||
| `VLM_TRACKS` | `comfyui-vlm/tracks`, version 1 | Durable object IDs with ordered observations over time |
|
||||
| `VLM_POINTS` | `comfyui-vlm/points`, version 1 | Pixel-coordinate points, including detection centers |
|
||||
| `VLM_EVENTS` | `comfyui-vlm/events`, version 1 | Ordered temporal events for downstream video analysis |
|
||||
| `VLM_VIDEO_SELECTION` | `comfyui-vlm/video-selection`, version 1 | Exact mapping from sampled images to source frame indices and timestamps |
|
||||
| `VLM_SCENE_STATE` | `comfyui-vlm/scene-state`, version 1 | Compact persistent objects, motion, visibility, and validated events |
|
||||
|
||||
All spatial coordinates are source-image pixels. Bounding boxes are
|
||||
`[x1, y1, x2, y2]` with an exclusive right/bottom edge; polygons contain at
|
||||
least three points and quads exactly four. JSON roots contain `schema`,
|
||||
`version`, media dimensions/frame count/FPS, and their ordered records. Dense
|
||||
mask tensors remain in-process and are deliberately omitted from JSON so API
|
||||
results do not unexpectedly grow by hundreds of megabytes.
|
||||
|
||||
The utility layer converts without model-specific glue:
|
||||
|
||||
- `VLMStructuredSpatialParser` strictly parses pixel, normalized 0–1, or
|
||||
normalized 0–1000 JSON from any VLM into `VLM_DETECTIONS` and `VLM_POINTS`.
|
||||
`VLMSpatialPromptBuilder` creates the matching constrained prompt.
|
||||
- `VLMDetectionsToBoundingBoxes`, `VLMDetectionsToPoints`, and
|
||||
`VLMDetectionsToMasks` emit Comfy core boxes, center points, combined and
|
||||
individual binary masks, inverse masks, ready-to-preview black-and-white
|
||||
images, and stable-color instance maps. Polygon/quad masks are rasterized
|
||||
when present, otherwise the bounding box is used. Existing output indexes
|
||||
remain stable; the creator-facing mask images and instance map are appended.
|
||||
- `VLMFilterDetections`, `VLMSelectDetection`, `VLMCropDetections`, and
|
||||
`VLMRenderDetections` provide label/score/area/frame selection, padded crops,
|
||||
and deterministic overlays.
|
||||
- `VLMMaskProcessor` accepts any Comfy `MASK`, including SAM2/SAM3 masks, and
|
||||
returns a feathered matte, strict binary mask, inverse mask, and
|
||||
black-and-white image. Its grow/shrink and Gaussian feathering run in Torch
|
||||
without OpenCV or SciPy.
|
||||
- `VLMMaskComposite` applies still-image or video mask batches to a source and
|
||||
returns the replacement composite, isolated foreground, original
|
||||
background-only plate, and black-and-white mask image. A single mask or
|
||||
background broadcasts safely across a video batch.
|
||||
- `VLMDetectionsFromJSON` and `VLMDetectionsToJSON` are the explicit API and
|
||||
persistence boundary for the versioned detection schema.
|
||||
|
||||
### Universal VLM performance utilities
|
||||
|
||||
The performance nodes sit before any local or hosted VLM, so their savings do
|
||||
not depend on CUDA, ROCm, MPS, XPU, CPU, Transformers, llama.cpp, or Photon:
|
||||
|
||||
- `VLM Performance Profile` emits coherent `max_frames`, pixel budget,
|
||||
longest-edge, batch-size, and `unload_after` values. `Live / robotics`,
|
||||
`Fast video`, `Balanced`, `High detail`, and `Low VRAM handoff` are explicit
|
||||
starting points rather than hidden global flags.
|
||||
- `VLM Adaptive Frame Sampler` is the existing track-aware temporal gate. It
|
||||
combines uniform coverage, scene changes, motion, and optional track changes
|
||||
while preserving source frame indices and timestamps.
|
||||
- `VLM Image Pixel Budget` downsizes the selected analysis copy once, preserves
|
||||
aspect ratio, never upscales, and can align dimensions to 14/28-pixel VLM
|
||||
patches or 32-pixel detector backbones. Fast area and antialiased bicubic
|
||||
modes are available.
|
||||
|
||||
The recommended order is `Video Slice` → `VLM Adaptive Frame Sampler` →
|
||||
`VLM Image Pixel Budget` → any VLM. A model's own official processor still
|
||||
performs its required normalization/crop; the pixel-budget node simply prevents
|
||||
every downstream model from repeatedly receiving unnecessary source pixels.
|
||||
Local torch models remain registered with ComfyUI's smart model manager, while
|
||||
external allocators reserve space before loading and close only the handle they
|
||||
own.
|
||||
|
||||
On the real `vlm_api_people_birds.mp4` input in this repository's D-drive test
|
||||
environment, the utilities selected 10 of 60 1280×720 frames and resized them
|
||||
to 938×518 in about 0.44 seconds on a cold WSL run. That reduced the
|
||||
frame×pixel analysis workload by 11.38× before model inference. This is an
|
||||
input-work reduction measurement, not a claim that every model runs 11.38×
|
||||
faster; token generation and model-specific vision encoders still determine
|
||||
end-to-end speed.
|
||||
|
||||
### Adaptive video intelligence
|
||||
|
||||
The video-intelligence layer keeps generative VLM inference out of the
|
||||
per-frame loop:
|
||||
|
||||
- `VLMAdaptiveFrameSampler` combines scene-change, motion, track-change, and
|
||||
uniform-coverage signals. It always preserves the real source frame index
|
||||
and timestamp, enforces a frame budget, and returns selection/diagnostic
|
||||
JSON. `Uniform coverage`, motion, scene, and track-priority modes remain
|
||||
available for deterministic experiments.
|
||||
- `VLMVideoTemporalReasoner` is the one-node path. It adaptively samples the
|
||||
input, downsizes only the VLM analysis copy (448-pixel longest side by
|
||||
default), runs a recommended video-capable model, parses the result into
|
||||
validated `VLM_EVENTS`, and returns summary, events, selection, sampled
|
||||
previews, raw response, diagnostics, event JSON, and selection JSON.
|
||||
- `VLMVideoReasoningPrompt` and `VLMEventsFromVideoJSON` expose the same strict
|
||||
timestamp/evidence contract for custom local or hosted VLM workflows.
|
||||
- `VLMTrackAwareCrops` chooses representative observations for each durable
|
||||
track, adds configurable context, and letterboxes crops to one batch size.
|
||||
This lets a VLM label identities without rereading every full frame.
|
||||
- `VLMBuildSceneState` converts tracks plus optional events into a compact
|
||||
persistent world-state summary with first/last observation, current box,
|
||||
confidence, state, and pixel velocity.
|
||||
|
||||
Small VLMs commonly return evidence as positions in the supplied image batch
|
||||
even when asked for source indices. The parser accepts that form only when
|
||||
every value is an unambiguous valid supplied-image position, maps it back to
|
||||
the immutable source selection, and records the normalization mode. Arbitrary
|
||||
or unsupplied evidence frames, out-of-range timestamps, invalid confidence,
|
||||
duplicate evidence, malformed JSON, and non-finite values fail validation.
|
||||
|
||||
On the repository's real-data smoke test (RTX 3090, Qwen3-VL 2B, 157-frame
|
||||
896x448 H.264 clip), hybrid sampling selected 12 frames in 0.30 seconds,
|
||||
reduced temporal inputs by 92.36%, reduced analysis pixels by 75%, used
|
||||
4.24 GiB peak allocated VRAM in the standalone runner, and produced a valid
|
||||
timestamped result in 35.17 seconds. The equivalent live ComfyUI `/prompt`
|
||||
graph completed in 37.45 seconds. These are one-machine measurements, not
|
||||
portable performance guarantees.
|
||||
|
||||
### Open-vocabulary image and video detection
|
||||
|
||||
`VLMOpenVocabularyDetection` exposes one interface for:
|
||||
|
||||
- Grounding DINO Tiny and Base
|
||||
- OWLv2 Base Ensemble
|
||||
- OmDet Turbo Swin Tiny
|
||||
|
||||
It accepts a still image or an `IMAGE` batch of video frames and processes the
|
||||
batch frame by frame. Outputs, in socket order, are `detections`, `json`,
|
||||
`preview`, `box_mask`, and Comfy core `bounding_boxes`. Connect the FPS output
|
||||
of `GetVideoComponents` when the input is video so every timestamp is correct.
|
||||
For tracking-by-detection, run detection over the complete bounded batch and
|
||||
connect it to `VLMTrackDetections`.
|
||||
|
||||
`VLMTrackDetections` uses a ByteTrack-style two-stage high/low-confidence
|
||||
association, motion prediction, label-aware matching, and time-based expiry.
|
||||
IDs are durable within the supplied sequence and survive short missed
|
||||
detections when `emit_predictions` is enabled. Independent Comfy queue runs or
|
||||
independently sliced chunks are separate tracking sessions; they do not
|
||||
silently reuse IDs.
|
||||
|
||||
### SAM2.1 and Comfy core SAM3.1
|
||||
|
||||
`VLMSAM2VideoSegmentation` propagates first-frame detections, one core
|
||||
`BOUNDING_BOX`, or seed masks through an `IMAGE` batch using SAM2.1 Hiera Tiny,
|
||||
Small, Base+, or Large. It returns `VLM_TRACKS`, report JSON, per-frame union
|
||||
masks, frame-major individual object masks, and an overlay batch. The object
|
||||
IDs assigned at the seed frame remain stable for that video session.
|
||||
|
||||
`VLMSAM3TrackAdapter` is intentionally an adapter, not a second SAM3 loader. It
|
||||
validates ComfyUI core `SAM3_TRACK_DATA`, preserves the core bit-packed mask
|
||||
payload unchanged, and exposes lightweight `VLM_TRACKS` metadata with mask
|
||||
references. Connect its passthrough output to core `SAM3_TrackPreview` or
|
||||
`SAM3_TrackToMask`, and connect `tracks` to `VLMTrackReport`. This avoids
|
||||
duplicating dense masks in memory or JSON.
|
||||
|
||||
SAM3 weights use Meta's SAM License. The upstream `facebook/sam3` repository
|
||||
requires accepting access terms and sharing the requested account information;
|
||||
the ComfyUI checkpoint is also marked `sam-license`. Review and accept the
|
||||
license before downloading. The example names ComfyUI's
|
||||
`sam3.1_multiplex_fp16.safetensors`; if it is unavailable, use the SAM2.1
|
||||
workflow rather than substituting an unrelated checkpoint.
|
||||
|
||||
### Florence-2 task coverage
|
||||
|
||||
`Florence2` exposes all 15 supported task contracts:
|
||||
|
||||
| Task | Extra input | Structured result |
|
||||
| --- | --- | --- |
|
||||
| Caption | none | text |
|
||||
| Detailed caption | none | text |
|
||||
| More detailed caption | none | text |
|
||||
| OCR | none | text |
|
||||
| OCR with regions | none | text plus quadrilateral regions |
|
||||
| Object detection | none | labeled boxes |
|
||||
| Dense region caption | none | captions with boxes |
|
||||
| Caption to phrase grounding | `text_input` | phrase boxes |
|
||||
| Referring expression segmentation | `text_input` | polygons and mask |
|
||||
| Region to segmentation | one `BOUNDING_BOX` per image | polygons and mask |
|
||||
| Open vocabulary detection | `text_input` | model-provided spatial records |
|
||||
| Region to category | one `BOUNDING_BOX` per image | text |
|
||||
| Region to description | one `BOUNDING_BOX` per image | text |
|
||||
| Region to OCR | one `BOUNDING_BOX` per image | text |
|
||||
| Region proposals | none | boxes |
|
||||
|
||||
Every task returns `text`, `structured_json`, `mask`, and `visualization`.
|
||||
Tasks that do not produce a spatial result return an empty mask and the source
|
||||
image visualization. Region tasks reject ambiguous multi-box input; use
|
||||
`VLMSelectDetection` to isolate the record, then supply exactly one core
|
||||
`BOUNDING_BOX` with the same pixel coordinates.
|
||||
|
||||
### Video memory strategy
|
||||
|
||||
- Trim long media with core `Video Slice`, then use `GetVideoComponents`.
|
||||
Downscale the complete frame batch before detection or segmentation and keep
|
||||
every frame at identical dimensions.
|
||||
- Grounding detection supports configurable micro-batches; keep `batch_size=1`
|
||||
for minimum VRAM or increase it when memory allows. It returns both nested
|
||||
per-frame core `BOUNDING_BOX` values and flat metadata-rich
|
||||
`BOUNDING_BOXES`.
|
||||
- SAM2.1 stores source video frames on CPU, keeps its inference state on CPU by
|
||||
default, and limits the vision-feature cache to one frame. Union masks and
|
||||
previews return on CPU. Full per-object mask volumes are opt-in with
|
||||
`mask_output=union_and_objects`; disable `render_preview` to avoid another
|
||||
full-resolution overlay copy on long clips.
|
||||
- Start with Grounding DINO Tiny plus SAM2.1 Hiera Tiny. Increase detector or
|
||||
segmenter size only after the pipeline is correct. `unload_after=false`
|
||||
caches one model per node instance; use `true` when another large model must
|
||||
run immediately afterward.
|
||||
- A `Video Slice` is an independent propagation session. For very long media,
|
||||
use bounded slices, reseed each slice, and keep the overlap/output mapping in
|
||||
the caller. The pack does not pretend IDs are globally stable across separate
|
||||
queues.
|
||||
- The SAM3 adapter never unpacks the complete mask volume for its report. Use
|
||||
core `SAM3_TrackToMask` only when a dense selected mask is actually needed.
|
||||
|
||||
API-format examples are in [`examples/vision`](examples/vision):
|
||||
|
||||
- [`grounding_dino_image_api.json`](examples/vision/grounding_dino_image_api.json)
|
||||
- [`moondream3_preview_svg_segment_api.json`](examples/vision/moondream3_preview_svg_segment_api.json)
|
||||
- [`moondream31_video_detect_api.json`](examples/vision/moondream31_video_detect_api.json)
|
||||
- [`sam2_video_tracking_api.json`](examples/vision/sam2_video_tracking_api.json)
|
||||
- [`sam3_core_adapter_blueprint_api.json`](examples/vision/sam3_core_adapter_blueprint_api.json)
|
||||
- [`video_temporal_reasoning_api.json`](examples/vision/video_temporal_reasoning_api.json)
|
||||
- [`vlm_performance_preflight_api.json`](examples/vision/vlm_performance_preflight_api.json)
|
||||
|
||||
The dependency-free text-toolkit example is
|
||||
[`examples/text_toolkit_api.json`](examples/text_toolkit_api.json).
|
||||
|
||||
Upload the named media to ComfyUI's input directory, adjust the filenames and
|
||||
labels, then submit the JSON object as the `prompt` value to `/prompt`. These
|
||||
are API graphs, not frontend workflow-export JSON.
|
||||
|
||||
## Install
|
||||
|
||||
Install through ComfyUI Manager, or clone into `ComfyUI/custom_nodes` and run:
|
||||
|
||||
```bash
|
||||
python -m pip install -r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements.txt
|
||||
```
|
||||
cd custom_nodes
|
||||
git clone https://github.com/gokayfem/ComfyUI_VLM_nodes.git
|
||||
|
||||
Run that command with ComfyUI's Python. Do not install or replace `torch` from
|
||||
this repository: ComfyUI's own installer selects CUDA, ROCm, XPU, Metal, or CPU.
|
||||
Current official bitsandbytes wheels are installed automatically only on their
|
||||
supported OS/architecture combinations. Unsupported machines retain all
|
||||
non-quantized nodes.
|
||||
|
||||
### Moondream 3 / 3.1 isolated runtime
|
||||
|
||||
Moondream's official Photon package pins Pillow below version 11 while
|
||||
current ComfyUI uses a newer Pillow. It therefore runs in a dedicated sidecar
|
||||
environment and never changes ComfyUI's Python packages. Read and accept the
|
||||
[Moondream Model License 1.0](https://moondream.ai/licenses/model/1.0), then
|
||||
create the environment under the registered `LLavacheckpoints` model folder.
|
||||
|
||||
Linux/WSL/macOS:
|
||||
|
||||
```bash
|
||||
runtime="ComfyUI/models/LLavacheckpoints/moondream31-runtime"
|
||||
uv venv "$runtime/.venv" --python 3.12
|
||||
uv pip install --python "$runtime/.venv/bin/python" \
|
||||
-r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements-moondream31.txt
|
||||
```
|
||||
## VLM Nodes
|
||||
Utilizes ```llama-cpp-python``` for integration of LLaVa models. You can load and use any VLM with LLaVa models in GGUF format with this nodes.
|
||||
You need to download the model similar to ```ggml-model-q4_k.gguf``` and it's clip projector similar to ```mmproj-model-f16.gguf``` from this repositories (in the files and versions).
|
||||
```python=>3.9``` is necessary.
|
||||
Put all of the files inside ```models/LLavacheckpoints```
|
||||
Note that every **model's clip projector** is different!
|
||||
- [LlaVa 1.6 Mistral 7B](https://huggingface.co/cjpais/llava-1.6-mistral-7b-gguf/)
|
||||
- [Nous Hermes 2 Vision](https://huggingface.co/billborkowski/llava-NousResearch_Nous-Hermes-2-Vision-GGUF)
|
||||
- [LlaVa 1.5 7B](https://huggingface.co/mys/ggml_llava-v1.5-7b/)
|
||||
- [LlaVa 1.5 13B](https://huggingface.co/mys/ggml_llava-v1.5-13b)
|
||||
- [BakLLaVa](https://huggingface.co/mys/ggml_bakllava-1)
|
||||
etc..
|
||||
## InternLM-XComposer2-VL Node
|
||||
Utilizes ```AutoGPTQ``` for integration of InternLM-XComposer2-VL Model. It will automatically download the necessary files into ```custom_nodes/ComfyUI_VLM_nodes/nodes/files_for_internlm```.
|
||||
This is one of the best models for visual perception.
|
||||
**Important Note : This model is heavy.**
|
||||
- [InternLM-XComposer2](https://huggingface.co/internlm/internlm-xcomposer2-vl-7b-4bit)
|
||||
|
||||
## Automatic Prompt Generation and Suggestion Nodes
|
||||
**Get Keyword** node: It can take LLava outputs and extract keywords from them.
|
||||
**LLava PromptGenerator** node: It can create prompts given descriptions or keywords using (input prompt could be Get Keyword or LLava output directly).
|
||||
**Suggester** node: It can generate 5 different prompts based on the original prompt using consistent in the options or random prompts using random in the options.
|
||||
Works best with **LLava 1.5** and **1.6**.
|
||||
Windows PowerShell:
|
||||
|
||||
**Play with the ```temperature``` for creative or consistent results. Higher the temperature more creative are the results.**
|
||||
If you want to dive deep into [LLM Settings](https://www.promptingguide.ai/introduction/settings)
|
||||
```powershell
|
||||
$runtime = "ComfyUI\models\LLavacheckpoints\moondream31-runtime"
|
||||
uv venv "$runtime\.venv" --python 3.12
|
||||
uv pip install --python "$runtime\.venv\Scripts\python.exe" `
|
||||
-r "ComfyUI\custom_nodes\ComfyUI_VLM_nodes\requirements-moondream31.txt"
|
||||
```
|
||||
|
||||
Outputs are JSON looking texts, you can see them as a text using JsonToText Node.
|
||||
You can see any string output with ViewText Node
|
||||
You can set any string input using SimpleText Node
|
||||
Utilizes ```llama-cpp-agents``` for getting structured outputs.
|
||||
## LLM Prompt Generation from text nodes
|
||||
The first Loader execution downloads the selected official model below that
|
||||
runtime's `cache` directory. Use `moondream3.1-9B-A2B` for query, caption,
|
||||
detection, and pointing. Use `moondream3-preview` only for the SVG segment
|
||||
skill; the final 3.1 model card does not list segment. Set the server-side
|
||||
`MOONDREAM_PYTHON` environment variable
|
||||
when using a different isolated environment. Do not put this path or any
|
||||
credential in a workflow.
|
||||
|
||||
**LLM PromptGenerator** node:
|
||||
[Qwen 1.8B Stable Diffusion Prompt](https://huggingface.co/hahahafofo/Qwen-1_8B-Stable-Diffusion-Prompt-GGUF)
|
||||
[IF prompt MKR](https://huggingface.co/impactframes/IFpromptMKR-7b-L2-gguf-q4_k_m)
|
||||
This LLM's works best for now for prompt generation.
|
||||
**LLMSampler** node: You can chat with any LLM in gguf format, you can use LLava models as an LLM also.
|
||||
Official Photon local inference currently supports NVIDIA Ampere-or-newer on
|
||||
Linux/Windows and Apple Silicon on macOS 13 or newer. It does not currently
|
||||
provide local ROCm, Intel GPU, or CPU execution. Those platforms retain every
|
||||
portable Transformers, GGUF, API, and vision utility node in this pack.
|
||||
|
||||
**API PromptGenerator** node: You can use ChatGPT and DeepSeek API's to create prompts. https://platform.deepseek.com/ gives 10m free tokens.
|
||||
- ChatGPT-4
|
||||
- ChatGPT-3.5
|
||||
- DeepSeek
|
||||
You can use them for simple chat also there is an option in the node.
|
||||
On CUDA 12 x86-64 systems the isolated requirements deliberately install
|
||||
`nvidia-cuda-runtime-cu12==12.9.79`. Kestrel 0.4.6's AOT kernels require the
|
||||
`cudaLibraryLoadData` entry point, which is absent from the CUDA 12.6 runtime
|
||||
bundled by cu126 PyTorch. This pin updates only Photon's private runtime; it
|
||||
does not replace ComfyUI's PyTorch build or the host NVIDIA driver.
|
||||
|
||||
## moondream Node
|
||||
This node is designed to work with the Moondream model, a powerful small vision language model built by @vikhyatk using SigLIP, Phi-1.5, and the LLaVa training dataset.
|
||||
The model boasts 1.6 billion parameters and is made available for research purposes only; commercial use is not allowed.
|
||||
It will automatically download the necessary files into ```custom_nodes/ComfyUI_VLM_nodes/nodes/files_for__moondream```
|
||||
## JoyTag Node
|
||||
@fpgamine's JoyTag is a state of the art AI vision model for tagging images, with a focus on sex positivity and inclusivity.
|
||||
It uses the Danbooru tagging schema, but works across a wide range of images, from hand drawn to photographic.
|
||||
It will automatically download the necessary files into ```custom_nodes/ComfyUI_VLM_nodes/nodes/files_for_joytagger```
|
||||
## Example LLaVa Nodes
|
||||
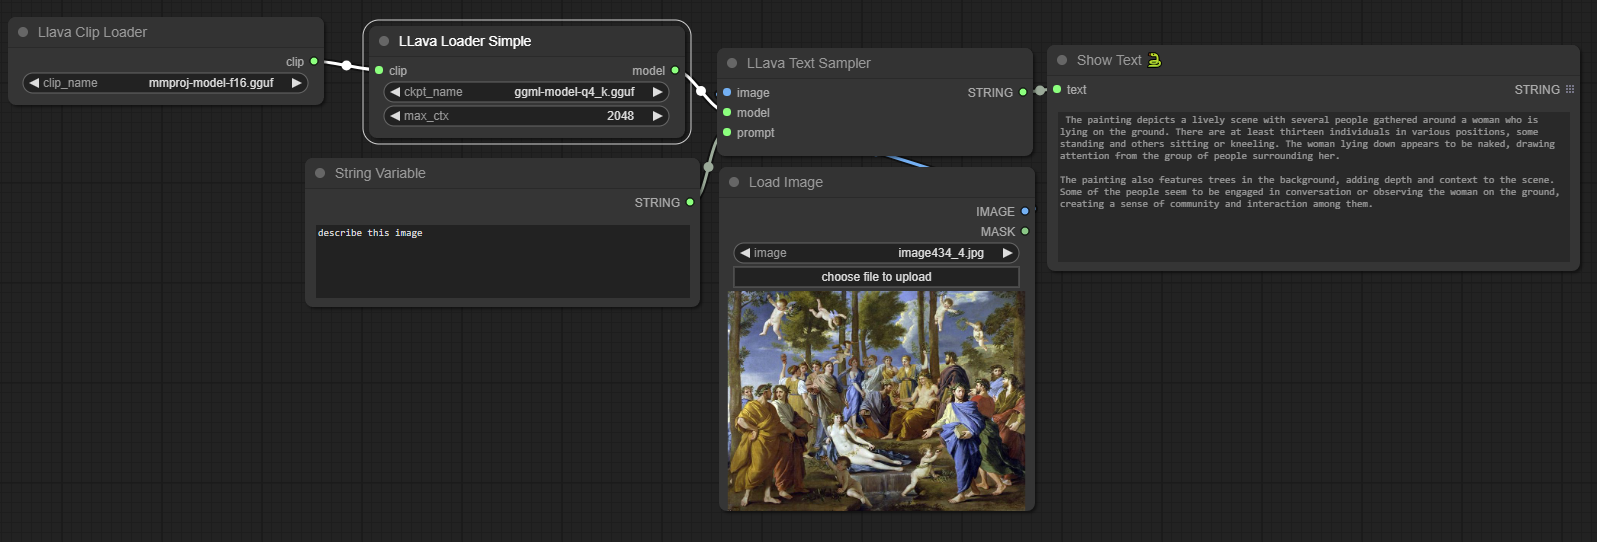
|
||||
GGUF nodes use optional `llama-cpp-python`. Install a wheel built for the
|
||||
desired CUDA, ROCm/HIP, Metal, Vulkan, SYCL, or CPU backend:
|
||||
|
||||
## Example InternLM-XComposer Node
|
||||
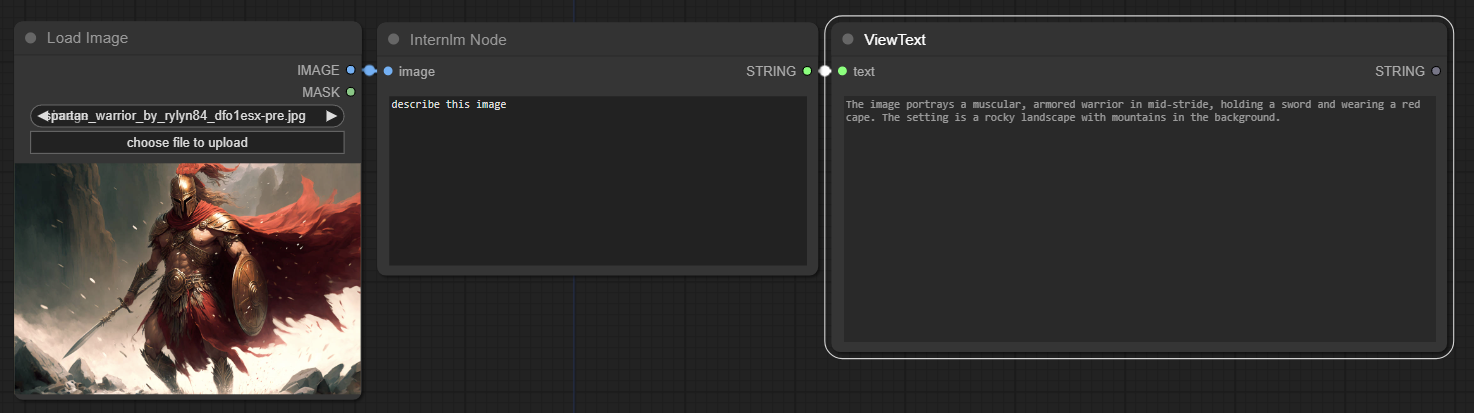
|
||||
```bash
|
||||
python -m pip install -r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements-llama-cpp.txt
|
||||
```
|
||||
|
||||
## Example Using Automatic Prompt Generation
|
||||
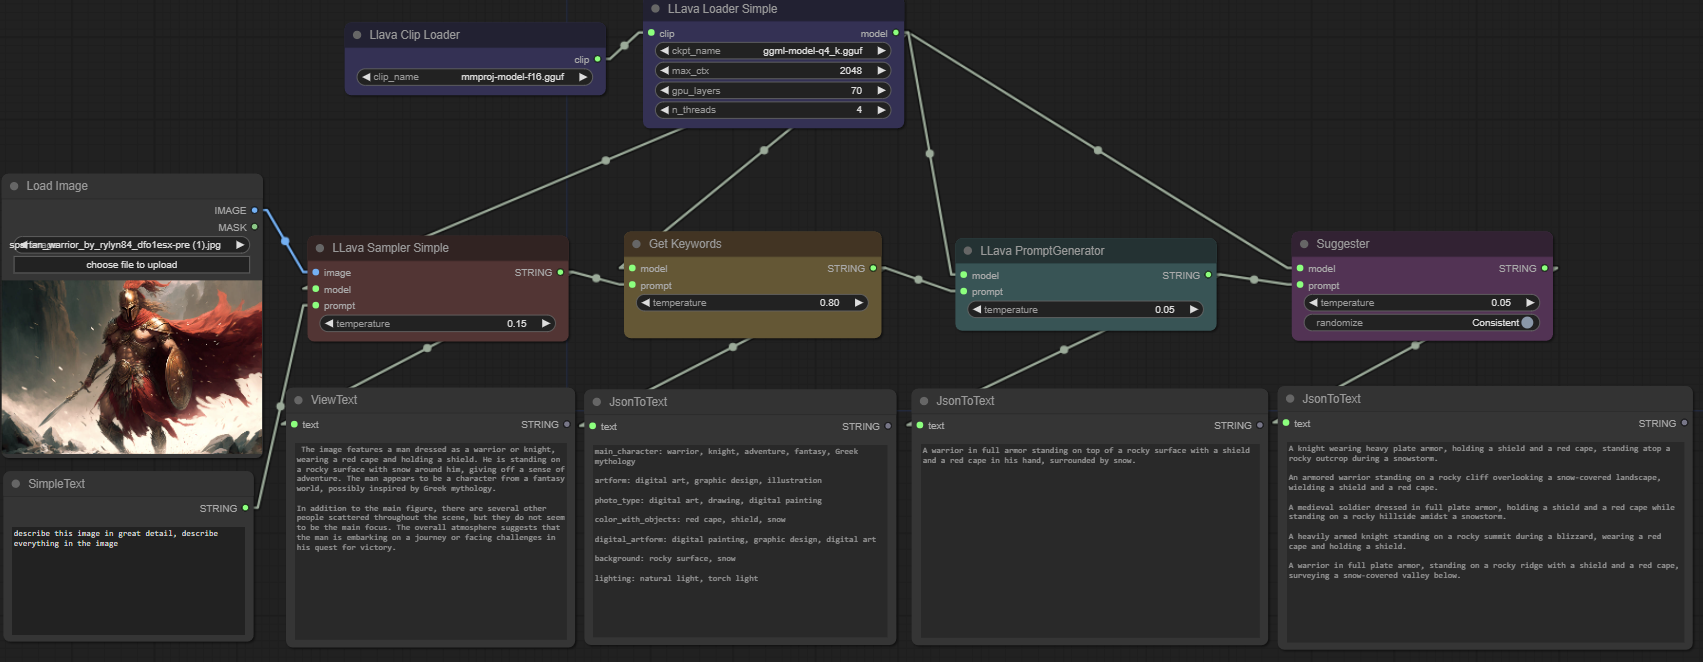
|
||||
See [COMPATIBILITY.md](COMPATIBILITY.md) for the tested matrix and official
|
||||
backend-specific GGUF commands.
|
||||
|
||||
## LLM Nodes
|
||||

|
||||
The GGUF loaders now query the installed llama.cpp build instead of inferring
|
||||
its capabilities from PyTorch. Accelerator offload automatically falls back to
|
||||
CPU when a CPU-only wheel is installed. Advanced optional inputs expose logical
|
||||
and physical prompt batching (`n_batch`/`n_ubatch`), flash-attention policy,
|
||||
mmap, and CUDA/ROCm multi-GPU layer/row splitting without changing legacy
|
||||
workflow sockets. `Auto` flash attention retries the portable path if a
|
||||
backend/model pair rejects it.
|
||||
|
||||
## Example moondream
|
||||
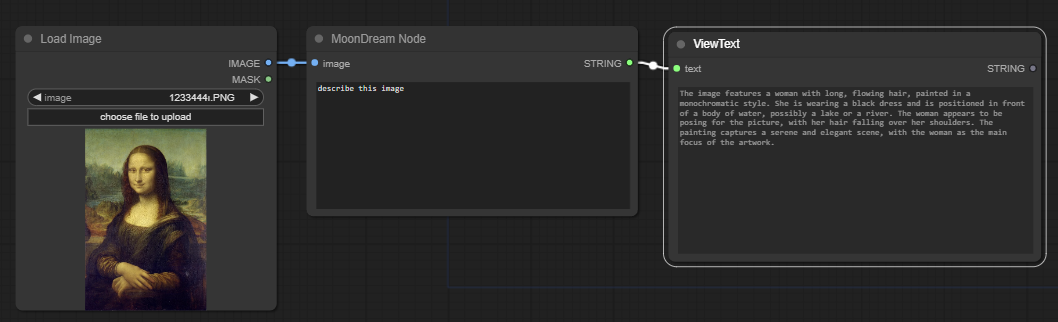
|
||||
The **LLaVA Vision Projector Loader** supports metadata-driven MTMD plus
|
||||
explicit handlers for LLaVA 1.5/1.6, MiniCPM-V 2.6, Moondream2, NanoLLaVA,
|
||||
Qwen2.5-VL, Gemma 4, Llama 3 Vision Alpha, and Obsidian. Use the default
|
||||
metadata-driven handler for current GGUF + mmproj pairs; select the named
|
||||
legacy handler when a model card requires it.
|
||||
|
||||
## Example Joytag
|
||||

|
||||
Models are downloaded only when their node first executes and are stored below
|
||||
`ComfyUI/models/LLavacheckpoints`. Hugging Face downloads respect `HF_TOKEN`.
|
||||
Gemma 3 and PaLI-Gemma require accepting their model licenses on Hugging Face.
|
||||
|
||||
## Example Prompt Generation
|
||||
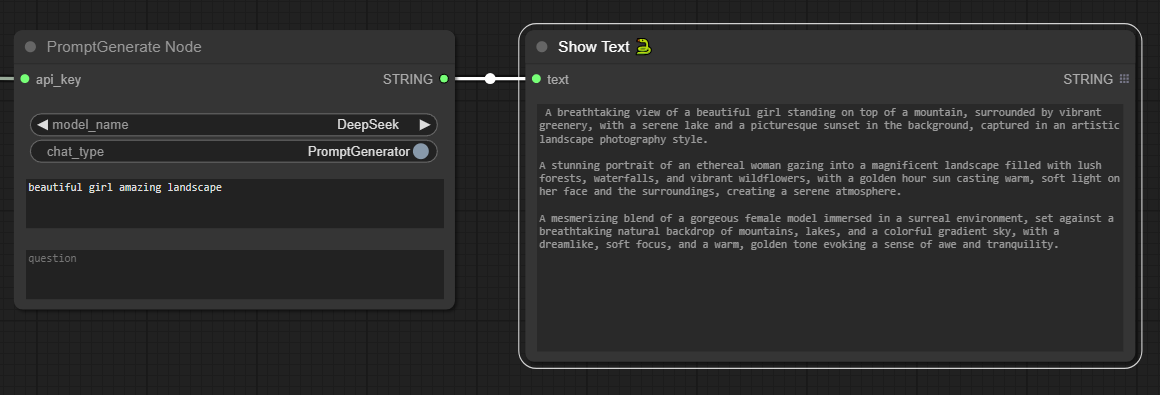
|
||||
## GPU lifecycle
|
||||
|
||||
## Example SimpleChat
|
||||
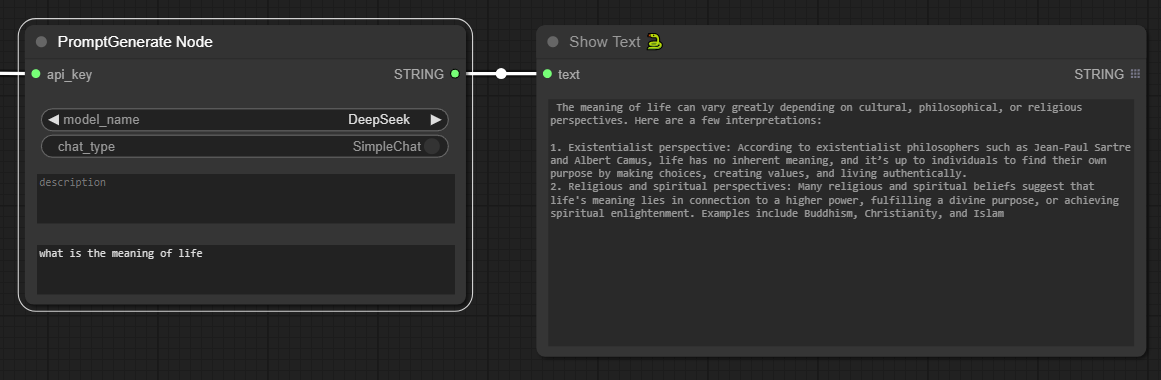
|
||||
- **ComfyUI managed (BF16)** is the default and preferred path. BF16 is used
|
||||
only when the active device reports support; otherwise the node safely falls
|
||||
back to FP16 on CUDA/ROCm/Metal/XPU or FP32 on CPU.
|
||||
- **4-bit/8-bit** models and llama.cpp own external allocators. Before loading,
|
||||
the nodes ask ComfyUI to free the required space; unloading closes the exact
|
||||
owned model and then requests a soft cache cleanup. Small quantized models
|
||||
stay on ComfyUI's active device instead of assuming GPU zero. Large-model
|
||||
Accelerate placement is enabled on CUDA/ROCm/XPU; any disk offload remains
|
||||
inside the model's ComfyUI directory.
|
||||
- llama.cpp model and projector bytes are included in the pre-load reservation.
|
||||
The runtime reports llama.cpp's own compiled backend, GPU-offload, mmap, and
|
||||
mlock capabilities in **VLM Runtime Diagnostics**.
|
||||
- `unload_after=false` caches one model per node instance for fast repeated
|
||||
queues. Cache creation is serialized, so concurrent API work cannot make the
|
||||
same node allocate duplicate model handles. Turn it on for maximum
|
||||
reclamation between prompts.
|
||||
- Moondream Photon asks ComfyUI to make room before it starts, then owns one
|
||||
exact isolated process. `unload_after=true` gracefully shuts it down and
|
||||
terminates that process if necessary, which releases Photon model, KV-cache,
|
||||
and CUDA-graph allocations without flushing unrelated ComfyUI models. The
|
||||
sidecar intentionally does not inherit ComfyUI's PyTorch allocator override;
|
||||
Photon's CUDA-graph capture uses the native allocator in its own process. The
|
||||
worker does not inherit unrelated provider keys or proxy credentials; only
|
||||
`HF_TOKEN`, and `MOONDREAM_API_KEY` for an explicitly selected adapter, may
|
||||
cross into its server-side environment. Base-model sidecars honor
|
||||
`DO_NOT_TRACK` locally and do not start Kestrel's anonymous telemetry task.
|
||||
Its random IPC secret is not placed on the process command line.
|
||||
- A connected `video_frames` batch becomes the primary visual input. The
|
||||
optional still-image socket is ignored for video inference so smaller models
|
||||
cannot silently answer from the wrong media.
|
||||
- Qwen 3.5/3.6 thinking is off by default for lower latency and predictable
|
||||
output length; enable it explicitly for tasks that benefit from visual
|
||||
reasoning.
|
||||
- **Auto (SDPA)** is portable and preferred. Flash Attention 2 is accepted only
|
||||
on supported CUDA/ROCm builds and otherwise fails before model loading.
|
||||
- **VLM Runtime Diagnostics** produces a zero-download JSON report containing
|
||||
OS, Python, PyTorch, backend, dtype capability, and optional package versions.
|
||||
- Visualization-only companion repositories do not allocate accelerator memory.
|
||||
|
||||
## Example LLava Sampler Advanced
|
||||
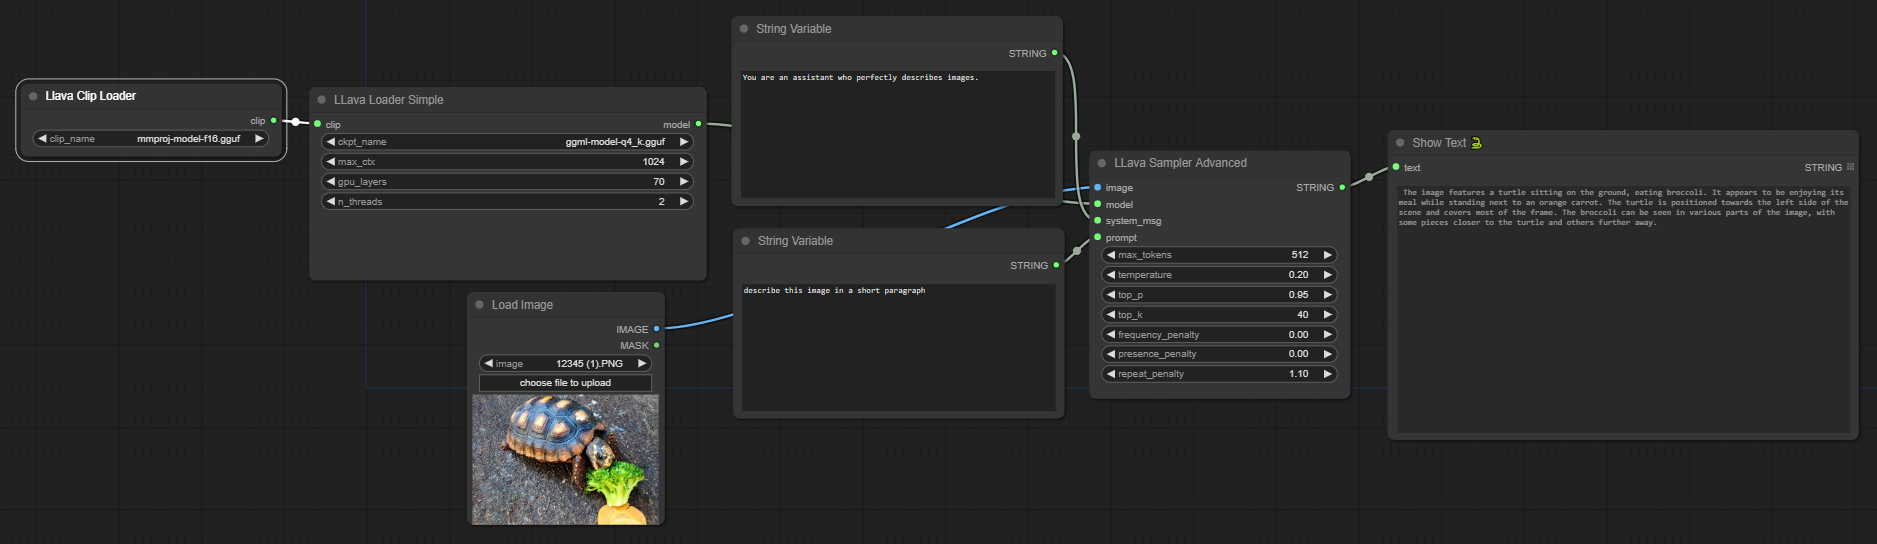
|
||||
Avoid placing several independently quantized VLMs in one workflow unless the
|
||||
GPU can hold them. On a 24 GB card, Qwen 3 VL 2B is the fast default,
|
||||
Qwen 3 VL 8B fits in BF16, and larger models should use NF4. Qwen 3.5/3.6 can
|
||||
be substantially slower when their optional optimized linear-attention kernels
|
||||
are not available for the installed PyTorch/backend combination.
|
||||
|
||||
## API nodes
|
||||
|
||||
**Hosted LLM API (Secure)** and **Hosted VLM API (Secure)** share a provider
|
||||
layer built around the current OpenAI Responses and Chat Completions request
|
||||
shapes, with Anthropic using its native Messages/vision contract and Gemini
|
||||
switching to its native multimodal contract for grounded or structured calls.
|
||||
The VLM node
|
||||
accepts a still image or a video-frame batch, samples
|
||||
frames uniformly, resizes and JPEG-compresses them, and enforces per-image and
|
||||
total request limits before upload. Both nodes can stream text into a connected
|
||||
`ViewText` node.
|
||||
|
||||
Both API nodes also expose:
|
||||
|
||||
- **Native web search** for OpenAI, Gemini, Anthropic, xAI, and any compatible
|
||||
model routed through OpenRouter. Unsupported presets fail clearly before a
|
||||
model request instead of silently pretending to search. Search can add
|
||||
provider cost and has provider-specific data terms, so it is off by default.
|
||||
- **JSON object** and **JSON Schema** output. Completed JSON is always parsed
|
||||
locally, JSON Schema results are validated locally, and invalid results fail
|
||||
the node instead of flowing into downstream automation.
|
||||
- **Open-source structured VLM output** through Custom / Local endpoints.
|
||||
OpenAI-standard mode supports vLLM, Ollama, and compatible servers;
|
||||
`llama.cpp JSON Schema` emits llama.cpp's direct schema dialect; and
|
||||
`JSON object + local validation` is a portable fallback for servers that
|
||||
implement only JSON mode.
|
||||
|
||||
User-provided schemas are capped at 64,000 characters, bounded by depth/node
|
||||
count, checked against their declared JSON Schema draft, and may use only local
|
||||
fragment `$ref` values. Remote/file references are rejected so validation can
|
||||
never turn into an unexpected network or filesystem lookup.
|
||||
|
||||
Curated production profiles include:
|
||||
|
||||
| Provider | Presets | Server environment variable |
|
||||
| --- | --- | --- |
|
||||
| OpenAI | GPT-5.6 Terra, Sol, Luna | `OPENAI_API_KEY` |
|
||||
| Google | Gemini 3.6 Flash, 3.5 Flash, 3.5 Flash-Lite | `GEMINI_API_KEY` |
|
||||
| Anthropic | Claude Fable 5, Opus 5, Sonnet 5, Haiku 4.5 | `ANTHROPIC_API_KEY` |
|
||||
| xAI | Grok 4.5 | `XAI_API_KEY` |
|
||||
| DeepSeek | V4 Flash, V4 Pro | `DEEPSEEK_API_KEY` |
|
||||
| Groq | Qwen 3.6 27B Vision, GPT-OSS 20B | `GROQ_API_KEY` |
|
||||
| Mistral | Mistral Large, Mistral Small, Ministral 14B | `MISTRAL_API_KEY` |
|
||||
| Together AI | Kimi K2.5, Qwen 3.5 9B | `TOGETHER_API_KEY` |
|
||||
| OpenRouter | Any compatible model ID | `OPENROUTER_API_KEY` |
|
||||
| Custom/local | OpenAI-compatible endpoint | `CUSTOM_API_KEY` |
|
||||
|
||||
Preset IDs were reviewed on 2026-07-29 against the official
|
||||
[OpenAI](https://developers.openai.com/api/docs/models),
|
||||
[Gemini](https://ai.google.dev/gemini-api/docs/models),
|
||||
[Claude](https://platform.claude.com/docs/en/about-claude/models/overview),
|
||||
[xAI](https://docs.x.ai/developers/models),
|
||||
[DeepSeek](https://api-docs.deepseek.com/updates/),
|
||||
[Groq](https://console.groq.com/docs/models),
|
||||
[Mistral](https://docs.mistral.ai/models/), and
|
||||
[Together](https://docs.together.ai/docs/inference/recommended-models), plus
|
||||
[OpenRouter's multimodal compatibility](https://openrouter.ai/docs/guides/overview/multimodal/overview)
|
||||
catalogs. Use `model_override` when a provider exposes a newer compatible model
|
||||
before the next node-pack release.
|
||||
|
||||
The capability routing follows the current official
|
||||
[OpenAI web-search](https://developers.openai.com/api/docs/guides/tools-web-search)
|
||||
and [structured-output](https://developers.openai.com/api/docs/guides/structured-outputs)
|
||||
contracts,
|
||||
[Gemini grounding](https://ai.google.dev/gemini-api/docs/google-search) and
|
||||
[structured output](https://ai.google.dev/gemini-api/docs/structured-output),
|
||||
[Claude web-search](https://platform.claude.com/docs/en/agents-and-tools/tool-use/web-search-tool)
|
||||
and [structured-output](https://platform.claude.com/docs/en/build-with-claude/structured-outputs)
|
||||
contracts, [xAI web search](https://docs.x.ai/developers/tools/web-search) and
|
||||
[structured outputs](https://docs.x.ai/developers/model-capabilities/text/structured-outputs),
|
||||
and [OpenRouter server-side search](https://openrouter.ai/docs/guides/features/server-tools/web-search).
|
||||
The local dialect is based on the
|
||||
[llama.cpp server API](https://github.com/ggml-org/llama.cpp/blob/master/tools/server/README.md).
|
||||
|
||||
API keys are not node inputs. A workflow contains only the provider selection,
|
||||
and the server resolves that provider's fixed environment variable at execution
|
||||
time. Built-in credentials are pinned to the provider's official HTTPS host;
|
||||
only the custom profile accepts a URL, and it can read only `CUSTOM_API_KEY`.
|
||||
Remote custom URLs require HTTPS, while keyless HTTP is restricted to
|
||||
`localhost`/loopback. Redirect following and environment proxies are disabled
|
||||
by default, API calls are stateless, OpenAI Responses explicitly use
|
||||
`store=false`, and provider exceptions are redacted before ComfyUI receives
|
||||
them.
|
||||
|
||||
Web search sends the prompt (and, where supported, the same multimodal request)
|
||||
to the selected provider's server-side search system. Do not enable it for
|
||||
content that must not be processed under that provider's search terms.
|
||||
|
||||
Opening an older `PromptGenerateAPI` workflow automatically clears its former
|
||||
plaintext key widget before the graph is configured. Save the migrated workflow
|
||||
to overwrite the old file, and rotate any key that was previously saved or
|
||||
shared. See [SECURITY.md](SECURITY.md) for setup and the exact threat model.
|
||||
|
||||
## Reliability guarantees
|
||||
|
||||
- Importing the pack performs no network access, compilation, or package install.
|
||||
- Missing optional backends fail only the node that needs them, with an
|
||||
actionable error.
|
||||
- Image inputs use ComfyUI `BHWC` batches; text responses preserve every batch
|
||||
item. Florence/PaLI masks use `BHW`.
|
||||
- `forceInput` string hacks were removed, preventing frontend widget-index drift.
|
||||
- Downloads stay inside the configured ComfyUI model directory.
|
||||
- CI installs and imports the full pack on Linux Python 3.10/3.13, Windows
|
||||
Python 3.12, and macOS Python 3.12. Backend contracts for CUDA, ROCm, Metal,
|
||||
XPU, and CPU are exercised without pretending hosted CPU runners are GPUs.
|
||||
|
||||
Run local checks with:
|
||||
|
||||
```bash
|
||||
PYTHONPATH=/path/to:/path/to/ComfyUI python -m pytest -q
|
||||
```
|
||||
|
||||
Real-weight checks are opt-in because they download multi-gigabyte checkpoints:
|
||||
|
||||
```bash
|
||||
python tests/manual_model_smoke.py --model "Qwen 3 VL 4B Instruct"
|
||||
python tests/manual_specialized_smoke.py --backend florence-large
|
||||
python tests/manual_llama_cpp_smoke.py --download
|
||||
```
|
||||
|
||||
See [MODEL_VALIDATION.md](MODEL_VALIDATION.md) for the exact real-weight and
|
||||
catalog-only evidence matrix.
|
||||
|
||||
Please report reproducible bugs at the
|
||||
[issue tracker](https://github.com/gokayfem/ComfyUI_VLM_nodes/issues).
|
||||
|
||||
+84
@@ -0,0 +1,84 @@
|
||||
# API credential security
|
||||
|
||||
## Guarantees
|
||||
|
||||
- API keys are never accepted as node inputs, widget values, workflow fields,
|
||||
outputs, metadata, or log messages.
|
||||
- Each built-in provider reads only its standard server-side environment
|
||||
variable and sends it only to that provider's fixed official HTTPS endpoint.
|
||||
- A built-in provider key cannot be combined with a workflow-supplied URL.
|
||||
- The custom endpoint reads only `CUSTOM_API_KEY`. Remote custom endpoints must
|
||||
use HTTPS; unencrypted and keyless requests are limited to loopback.
|
||||
- HTTP redirects and environment proxies are disabled by default. Proxy use is
|
||||
an explicit non-secret node option for installations that require it.
|
||||
- Hosted calls are stateless. No Python node-instance conversation history is
|
||||
retained, and OpenAI Responses requests set `store=false`.
|
||||
- Exceptions are bounded and redact the resolved key, URL-encoded variants,
|
||||
bearer tokens, common provider-key formats, authorization fields, and URL
|
||||
user-info before the message reaches ComfyUI.
|
||||
- Local image/video-frame uploads are uniformly sampled, resized,
|
||||
JPEG-compressed, limited to 4 MiB per image, and limited to 24 MiB total.
|
||||
- User JSON Schemas are size/depth/node bounded and may contain only local
|
||||
fragment `$ref` values. Remote URLs and file references are rejected before
|
||||
validation, preventing schema resolution from becoming an SSRF or local-file
|
||||
access path.
|
||||
|
||||
## Configure credentials
|
||||
|
||||
Set the matching variable in the environment that launches ComfyUI, then
|
||||
restart ComfyUI:
|
||||
|
||||
| Provider | Variable |
|
||||
| --- | --- |
|
||||
| OpenAI | `OPENAI_API_KEY` |
|
||||
| Google Gemini | `GEMINI_API_KEY` |
|
||||
| Anthropic | `ANTHROPIC_API_KEY` |
|
||||
| xAI | `XAI_API_KEY` |
|
||||
| DeepSeek | `DEEPSEEK_API_KEY` |
|
||||
| Groq | `GROQ_API_KEY` |
|
||||
| Mistral | `MISTRAL_API_KEY` |
|
||||
| Together AI | `TOGETHER_API_KEY` |
|
||||
| OpenRouter | `OPENROUTER_API_KEY` |
|
||||
| Custom remote endpoint | `CUSTOM_API_KEY` |
|
||||
|
||||
For an interactive POSIX/WSL session, this avoids putting the value in shell
|
||||
history:
|
||||
|
||||
```bash
|
||||
read -rsp "Provider API key: " OPENAI_API_KEY
|
||||
export OPENAI_API_KEY
|
||||
python main.py
|
||||
```
|
||||
|
||||
Use the equivalent secret manager or service environment mechanism for a
|
||||
persistent installation. Do not commit a `.env` file, workflow containing an
|
||||
old key, shell script containing a key, or copied ComfyUI log.
|
||||
|
||||
Web search is disabled by default. Enabling it sends the request content to the
|
||||
selected provider's server-side search system and may have separate retention,
|
||||
regional-availability, and billing terms. Treat it as an explicit data-sharing
|
||||
choice; do not enable it for content that is outside those terms.
|
||||
|
||||
## Legacy workflows
|
||||
|
||||
Versions before this security update exposed an `api_key` text widget.
|
||||
The frontend migration clears position 3 of every serialized
|
||||
`PromptGenerateAPI` node before LiteGraph creates the active node, including
|
||||
nodes inside saved subgraph definitions. The backend independently rejects any
|
||||
value that is not one of the two safe credential-source choices.
|
||||
|
||||
The source workflow file is not rewritten merely by opening it. Save the
|
||||
migrated workflow, securely remove old copies, and rotate any credential that
|
||||
was ever saved, shared, committed, backed up, or placed in an exported PNG.
|
||||
|
||||
## Threat boundary
|
||||
|
||||
ComfyUI custom nodes execute Python code with the permissions of the ComfyUI
|
||||
process. Another untrusted custom-node package can read the same process
|
||||
environment regardless of protections in this repository. Install only trusted
|
||||
node packs, keep ComfyUI authenticated and bound to a trusted interface, and do
|
||||
not expose an unauthenticated server to the public internet.
|
||||
|
||||
If a key may have been exposed, revoke it with the provider immediately, review
|
||||
usage, create a replacement with the minimum needed project permissions and
|
||||
spend limit, and restart ComfyUI with the replacement.
|
||||
+51
-42
@@ -1,56 +1,65 @@
|
||||
import importlib.util
|
||||
import os
|
||||
import importlib
|
||||
import pkg_resources
|
||||
import sys
|
||||
import subprocess
|
||||
import logging
|
||||
|
||||
# Define the check_requirements_installed function here or import it
|
||||
def check_requirements_installed(requirements_path):
|
||||
with open(requirements_path, 'r') as f:
|
||||
requirements = [pkg_resources.Requirement.parse(line.strip()) for line in f if line.strip()]
|
||||
from .nodes.runtime import register_model_folder
|
||||
|
||||
installed_packages = {pkg.key: pkg for pkg in pkg_resources.working_set}
|
||||
missing_packages = []
|
||||
for requirement in requirements:
|
||||
if requirement.key not in installed_packages or not installed_packages[requirement.key] in requirement:
|
||||
missing_packages.append(str(requirement))
|
||||
|
||||
if missing_packages:
|
||||
print(f"Missing or outdated packages: {', '.join(missing_packages)}")
|
||||
print("Installing/Updating missing packages...")
|
||||
subprocess.check_call([sys.executable, '-s', '-m', 'pip', 'install', *missing_packages])
|
||||
else:
|
||||
print("All packages from requirements.txt are installed and up to date.")
|
||||
requirements_path = os.path.join(os.path.dirname(os.path.realpath(__file__)), "requirements.txt")
|
||||
check_requirements_installed(requirements_path)
|
||||
|
||||
from .install_init import init, get_system_info, install_llama, install_autogptq
|
||||
system_info = get_system_info()
|
||||
install_llama(system_info)
|
||||
llama_cpp_agent_path = os.path.join(os.path.dirname(os.path.realpath(__file__)), "cpp_agent_req.txt")
|
||||
check_requirements_installed(llama_cpp_agent_path)
|
||||
install_autogptq(system_info)
|
||||
init()
|
||||
LOGGER = logging.getLogger("ComfyUI_VLM_nodes")
|
||||
register_model_folder()
|
||||
|
||||
node_list = [
|
||||
"moondream_script",
|
||||
"simpletext",
|
||||
"llavaloader",
|
||||
"suggest",
|
||||
"acceleration",
|
||||
"audioldm2",
|
||||
"diagnostics",
|
||||
"florence2",
|
||||
"grounding",
|
||||
"hosted_api",
|
||||
"joytag",
|
||||
"internlm",
|
||||
"kosmos2",
|
||||
"llavaloader",
|
||||
"mcllava",
|
||||
"minicpm",
|
||||
"modern_vlm",
|
||||
"molmo",
|
||||
"moondream31",
|
||||
"moondream2",
|
||||
"moondream_script",
|
||||
"paligemma",
|
||||
"playmusic",
|
||||
"qwen2vl",
|
||||
"sam2",
|
||||
"sam3_adapter",
|
||||
"simpletext",
|
||||
"spatial_parser",
|
||||
"suggest",
|
||||
"tracking",
|
||||
"uform",
|
||||
"video_intelligence",
|
||||
"vision_utils",
|
||||
]
|
||||
|
||||
NODE_CLASS_MAPPINGS = {}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {}
|
||||
IMPORT_ERRORS = {}
|
||||
|
||||
for module_name in node_list:
|
||||
imported_module = importlib.import_module(f".nodes.{module_name}", __name__)
|
||||
|
||||
NODE_CLASS_MAPPINGS = {**NODE_CLASS_MAPPINGS, **imported_module.NODE_CLASS_MAPPINGS}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {**NODE_DISPLAY_NAME_MAPPINGS, **imported_module.NODE_DISPLAY_NAME_MAPPINGS}
|
||||
try:
|
||||
imported_module = importlib.import_module(f".nodes.{module_name}", __name__)
|
||||
except Exception as exc:
|
||||
# A broken optional model must never prevent unrelated nodes from loading.
|
||||
IMPORT_ERRORS[module_name] = f"{type(exc).__name__}: {exc}"
|
||||
LOGGER.exception("Could not load optional node module %s", module_name)
|
||||
continue
|
||||
NODE_CLASS_MAPPINGS.update(
|
||||
getattr(imported_module, "NODE_CLASS_MAPPINGS", {})
|
||||
)
|
||||
NODE_DISPLAY_NAME_MAPPINGS.update(
|
||||
getattr(imported_module, "NODE_DISPLAY_NAME_MAPPINGS", {})
|
||||
)
|
||||
|
||||
|
||||
__all__ = ["NODE_CLASS_MAPPINGS", "NODE_DISPLAY_NAME_MAPPINGS"]
|
||||
|
||||
WEB_DIRECTORY = "./web"
|
||||
__all__ = [
|
||||
"NODE_CLASS_MAPPINGS",
|
||||
"NODE_DISPLAY_NAME_MAPPINGS",
|
||||
"WEB_DIRECTORY",
|
||||
]
|
||||
|
||||
@@ -1,5 +0,0 @@
|
||||
llama-cpp-agent
|
||||
mkdocs
|
||||
mkdocs-material
|
||||
mkdocstrings[python]
|
||||
docstring-parser
|
||||
@@ -0,0 +1,690 @@
|
||||
{
|
||||
"last_node_id": 43,
|
||||
"last_link_id": 54,
|
||||
"nodes": [
|
||||
{
|
||||
"id": 31,
|
||||
"type": "LlavaClipLoader",
|
||||
"pos": [
|
||||
439.6340175903321,
|
||||
172.3240056098938
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 58
|
||||
},
|
||||
"flags": {},
|
||||
"order": 0,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "clip",
|
||||
"type": "CUSTOM",
|
||||
"links": [
|
||||
37
|
||||
],
|
||||
"shape": 3
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LlavaClipLoader"
|
||||
},
|
||||
"widgets_values": [
|
||||
"mistrallava16clip.gguf"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 35,
|
||||
"type": "SimpleText",
|
||||
"pos": [
|
||||
1145.0176354455555,
|
||||
158.27893214202888
|
||||
],
|
||||
"size": {
|
||||
"0": 378.79046630859375,
|
||||
"1": 186.27911376953125
|
||||
},
|
||||
"flags": {},
|
||||
"order": 1,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "STRING",
|
||||
"type": "STRING",
|
||||
"links": [
|
||||
41
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "SimpleText"
|
||||
},
|
||||
"widgets_values": [
|
||||
"You are an advanced AI that shortens descriptions into sentences.\n\nExample 1: Birds singing sweetly in a blooming garden\nExample 2: A modern synthesizer creating futuristic soundscapes\nExample 3: The vibrant beat of Brazilian samba drums"
|
||||
],
|
||||
"color": "#232",
|
||||
"bgcolor": "#353"
|
||||
},
|
||||
{
|
||||
"id": 32,
|
||||
"type": "SimpleText",
|
||||
"pos": [
|
||||
439.6340175903321,
|
||||
452.3240056098937
|
||||
],
|
||||
"size": {
|
||||
"0": 318.79754638671875,
|
||||
"1": 82.05603790283203
|
||||
},
|
||||
"flags": {},
|
||||
"order": 2,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "STRING",
|
||||
"type": "STRING",
|
||||
"links": [
|
||||
38
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "SimpleText"
|
||||
},
|
||||
"widgets_values": [
|
||||
"describe this image in short, concisely"
|
||||
],
|
||||
"color": "#232",
|
||||
"bgcolor": "#353"
|
||||
},
|
||||
{
|
||||
"id": 38,
|
||||
"type": "SimpleText",
|
||||
"pos": [
|
||||
647.6433994140625,
|
||||
1010.9179632824712
|
||||
],
|
||||
"size": {
|
||||
"0": 318.79754638671875,
|
||||
"1": 82.05603790283203
|
||||
},
|
||||
"flags": {},
|
||||
"order": 3,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "STRING",
|
||||
"type": "STRING",
|
||||
"links": [
|
||||
45
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "SimpleText"
|
||||
},
|
||||
"widgets_values": [
|
||||
"Low quality, average quality."
|
||||
],
|
||||
"color": "#322",
|
||||
"bgcolor": "#533"
|
||||
},
|
||||
{
|
||||
"id": 29,
|
||||
"type": "LLavaSamplerSimple",
|
||||
"pos": [
|
||||
769.6340175903323,
|
||||
182.3240056098938
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 102
|
||||
},
|
||||
"flags": {},
|
||||
"order": 6,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "image",
|
||||
"type": "IMAGE",
|
||||
"link": 39,
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "model",
|
||||
"type": "CUSTOM",
|
||||
"link": 36,
|
||||
"slot_index": 1
|
||||
},
|
||||
{
|
||||
"name": "prompt",
|
||||
"type": "STRING",
|
||||
"link": 38,
|
||||
"widget": {
|
||||
"name": "prompt"
|
||||
},
|
||||
"slot_index": 2
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "STRING",
|
||||
"type": "STRING",
|
||||
"links": [
|
||||
42,
|
||||
43
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LLavaSamplerSimple"
|
||||
},
|
||||
"widgets_values": [
|
||||
"",
|
||||
0.1
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 36,
|
||||
"type": "ViewText",
|
||||
"pos": [
|
||||
774,
|
||||
325
|
||||
],
|
||||
"size": {
|
||||
"0": 303.2503967285156,
|
||||
"1": 156.48916625976562
|
||||
},
|
||||
"flags": {},
|
||||
"order": 8,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "text",
|
||||
"type": "STRING",
|
||||
"link": 43,
|
||||
"widget": {
|
||||
"name": "text"
|
||||
}
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "STRING",
|
||||
"type": "STRING",
|
||||
"links": null,
|
||||
"shape": 3
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "ViewText"
|
||||
},
|
||||
"widgets_values": [
|
||||
"",
|
||||
" The image shows a group of dancers performing on stage. They are dressed in colorful costumes with vibrant patterns and shades of green, yellow, and pink. The dancers appear to be in motion, suggesting they are dancing. The lighting is dim, which highlights the performers and creates a dramatic atmosphere. There is no visible text or branding in the image. The style of the image is a candid photograph capturing a live performance. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 30,
|
||||
"type": "LLava Loader Simple",
|
||||
"pos": [
|
||||
439.6340175903321,
|
||||
272.3240056098937
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 130
|
||||
},
|
||||
"flags": {},
|
||||
"order": 5,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "clip",
|
||||
"type": "CUSTOM",
|
||||
"link": 37,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "model",
|
||||
"type": "CUSTOM",
|
||||
"links": [
|
||||
36,
|
||||
40
|
||||
],
|
||||
"shape": 3
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LLava Loader Simple"
|
||||
},
|
||||
"widgets_values": [
|
||||
"llava-v1.6-mistral-7b.Q5_K_M.gguf",
|
||||
2048,
|
||||
100,
|
||||
2
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 33,
|
||||
"type": "LoadImage",
|
||||
"pos": [
|
||||
100,
|
||||
172
|
||||
],
|
||||
"size": {
|
||||
"0": 328.0104675292969,
|
||||
"1": 361.09918212890625
|
||||
},
|
||||
"flags": {},
|
||||
"order": 4,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
39
|
||||
],
|
||||
"shape": 3
|
||||
},
|
||||
{
|
||||
"name": "MASK",
|
||||
"type": "MASK",
|
||||
"links": null,
|
||||
"shape": 3
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadImage"
|
||||
},
|
||||
"widgets_values": [
|
||||
"412342132.PNG",
|
||||
"image"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 34,
|
||||
"type": "LLMSampler",
|
||||
"pos": [
|
||||
1536,
|
||||
193
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 298
|
||||
},
|
||||
"flags": {},
|
||||
"order": 7,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "model",
|
||||
"type": "CUSTOM",
|
||||
"link": 40,
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "prompt",
|
||||
"type": "STRING",
|
||||
"link": 42,
|
||||
"widget": {
|
||||
"name": "prompt"
|
||||
},
|
||||
"slot_index": 1
|
||||
},
|
||||
{
|
||||
"name": "system_msg",
|
||||
"type": "STRING",
|
||||
"link": 41,
|
||||
"widget": {
|
||||
"name": "system_msg"
|
||||
}
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "STRING",
|
||||
"type": "STRING",
|
||||
"links": [
|
||||
44,
|
||||
48
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LLMSampler"
|
||||
},
|
||||
"widgets_values": [
|
||||
"You are an assistant who perfectly describes images.",
|
||||
"",
|
||||
512,
|
||||
0.1,
|
||||
0.95,
|
||||
40,
|
||||
0,
|
||||
0,
|
||||
1.1,
|
||||
617,
|
||||
"randomize"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 40,
|
||||
"type": "ViewText",
|
||||
"pos": [
|
||||
1162,
|
||||
399
|
||||
],
|
||||
"size": {
|
||||
"0": 345.2934265136719,
|
||||
"1": 106.57048034667969
|
||||
},
|
||||
"flags": {},
|
||||
"order": 10,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "text",
|
||||
"type": "STRING",
|
||||
"link": 48,
|
||||
"widget": {
|
||||
"name": "text"
|
||||
}
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "STRING",
|
||||
"type": "STRING",
|
||||
"links": null,
|
||||
"shape": 3
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "ViewText"
|
||||
},
|
||||
"widgets_values": [
|
||||
"",
|
||||
" Dancers in colorful costumes performing on stage under dim lighting. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 43,
|
||||
"type": "PlayMusic",
|
||||
"pos": [
|
||||
1033,
|
||||
720
|
||||
],
|
||||
"size": [
|
||||
315,
|
||||
130
|
||||
],
|
||||
"flags": {},
|
||||
"order": 11,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "wave_form",
|
||||
"type": "COMBO",
|
||||
"link": 53,
|
||||
"widget": {
|
||||
"name": "wave_form"
|
||||
}
|
||||
},
|
||||
{
|
||||
"name": "sample_rate",
|
||||
"type": "INT",
|
||||
"link": 54,
|
||||
"widget": {
|
||||
"name": "sample_rate"
|
||||
}
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "*",
|
||||
"type": "*",
|
||||
"links": null,
|
||||
"shape": 6
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "PlayMusic"
|
||||
},
|
||||
"widgets_values": [
|
||||
"always",
|
||||
0.5,
|
||||
null,
|
||||
0
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 37,
|
||||
"type": "AudioLDM2Node",
|
||||
"pos": [
|
||||
666,
|
||||
725
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 222
|
||||
},
|
||||
"flags": {},
|
||||
"order": 9,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "text",
|
||||
"type": "STRING",
|
||||
"link": 44,
|
||||
"widget": {
|
||||
"name": "text"
|
||||
}
|
||||
},
|
||||
{
|
||||
"name": "negative_prompt",
|
||||
"type": "STRING",
|
||||
"link": 45,
|
||||
"widget": {
|
||||
"name": "negative_prompt"
|
||||
},
|
||||
"slot_index": 1
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "wave_form",
|
||||
"type": "*",
|
||||
"links": [
|
||||
53
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "sample_rate",
|
||||
"type": "INT",
|
||||
"links": [
|
||||
54
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 1
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "AudioLDM2Node"
|
||||
},
|
||||
"widgets_values": [
|
||||
"",
|
||||
"",
|
||||
10,
|
||||
3.5,
|
||||
995,
|
||||
"randomize",
|
||||
3,
|
||||
16000,
|
||||
"mp3"
|
||||
]
|
||||
}
|
||||
],
|
||||
"links": [
|
||||
[
|
||||
36,
|
||||
30,
|
||||
0,
|
||||
29,
|
||||
1,
|
||||
"CUSTOM"
|
||||
],
|
||||
[
|
||||
37,
|
||||
31,
|
||||
0,
|
||||
30,
|
||||
0,
|
||||
"CUSTOM"
|
||||
],
|
||||
[
|
||||
38,
|
||||
32,
|
||||
0,
|
||||
29,
|
||||
2,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
39,
|
||||
33,
|
||||
0,
|
||||
29,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
40,
|
||||
30,
|
||||
0,
|
||||
34,
|
||||
0,
|
||||
"CUSTOM"
|
||||
],
|
||||
[
|
||||
41,
|
||||
35,
|
||||
0,
|
||||
34,
|
||||
2,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
42,
|
||||
29,
|
||||
0,
|
||||
34,
|
||||
1,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
43,
|
||||
29,
|
||||
0,
|
||||
36,
|
||||
0,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
44,
|
||||
34,
|
||||
0,
|
||||
37,
|
||||
0,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
45,
|
||||
38,
|
||||
0,
|
||||
37,
|
||||
1,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
48,
|
||||
34,
|
||||
0,
|
||||
40,
|
||||
0,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
53,
|
||||
37,
|
||||
0,
|
||||
43,
|
||||
0,
|
||||
"COMBO"
|
||||
],
|
||||
[
|
||||
54,
|
||||
37,
|
||||
1,
|
||||
43,
|
||||
1,
|
||||
"INT"
|
||||
]
|
||||
],
|
||||
"groups": [
|
||||
{
|
||||
"title": "VLM",
|
||||
"bounding": [
|
||||
90,
|
||||
98,
|
||||
1005,
|
||||
446
|
||||
],
|
||||
"color": "#3f789e",
|
||||
"font_size": 24,
|
||||
"locked": false
|
||||
},
|
||||
{
|
||||
"title": "LLM",
|
||||
"bounding": [
|
||||
1135,
|
||||
84,
|
||||
733,
|
||||
491
|
||||
],
|
||||
"color": "#a1309b",
|
||||
"font_size": 24,
|
||||
"locked": false
|
||||
},
|
||||
{
|
||||
"title": "Sound",
|
||||
"bounding": [
|
||||
638,
|
||||
667,
|
||||
711,
|
||||
436
|
||||
],
|
||||
"color": "#b58b2a",
|
||||
"font_size": 24,
|
||||
"locked": false
|
||||
}
|
||||
],
|
||||
"config": {},
|
||||
"extra": {},
|
||||
"version": 0.4
|
||||
}
|
||||
@@ -0,0 +1,57 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "SimpleText",
|
||||
"inputs": {
|
||||
"input_text": "Model response:\n```json\n{\"scene\":{\"subject\":\"warehouse robot\",\"action\":\"moving a blue crate\"}}\n```"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "VLMJSONExtract",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"1",
|
||||
0
|
||||
],
|
||||
"path": "$.scene.action",
|
||||
"output_format": "Text",
|
||||
"if_missing": "Error",
|
||||
"default_value": ""
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "VLMTextTemplate",
|
||||
"inputs": {
|
||||
"template": "{instruction}\n\nObserved action: {text1}",
|
||||
"variables_json": "{\"instruction\":\"Write one concise video-generation prompt.\"}",
|
||||
"missing_values": "Error",
|
||||
"text1": [
|
||||
"2",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "VLMTextClean",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"3",
|
||||
0
|
||||
],
|
||||
"unicode_normalization": "NFC",
|
||||
"whitespace": "Normalize line endings",
|
||||
"trim_edges": true,
|
||||
"remove_outer_markdown_fence": false,
|
||||
"deduplicate_lines": false,
|
||||
"max_characters": 0
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"4",
|
||||
0
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,124 @@
|
||||
# Vision API examples
|
||||
|
||||
These files contain ComfyUI API prompt graphs: the object that belongs under
|
||||
the `prompt` key in a `POST /prompt` request. They are not frontend workflow
|
||||
exports and are not intended for drag-and-drop import into the canvas.
|
||||
|
||||
Before queueing:
|
||||
|
||||
1. Copy the named image/video into `ComfyUI/input`, or change the `image`/`file`
|
||||
widget value to an existing input filename.
|
||||
2. Restart ComfyUI after installing or updating this node pack.
|
||||
3. Confirm every `class_type` is present in `/object_info`.
|
||||
4. Wrap the loaded JSON as `{"prompt": graph}` in the API request.
|
||||
|
||||
## Examples
|
||||
|
||||
### `grounding_dino_image_api.json`
|
||||
|
||||
Runs Grounding DINO Tiny over `grounding_input.png`. Node 2 outputs:
|
||||
|
||||
| Index | Output |
|
||||
| ---: | --- |
|
||||
| 0 | `VLM_DETECTIONS` |
|
||||
| 1 | Structured detection JSON |
|
||||
| 2 | Detection overlay |
|
||||
| 3 | Box mask |
|
||||
| 4 | Core nested per-frame `BOUNDING_BOX` |
|
||||
| 5 | Flat metadata-rich `BOUNDING_BOXES` |
|
||||
|
||||
`PreviewImage` displays output 2 and `ViewText` reports output 1.
|
||||
|
||||
### `vlm_performance_preflight_api.json`
|
||||
|
||||
Loads `vlm_api_people_birds.mp4` with Comfy core video nodes, applies the
|
||||
`Fast video` performance profile, runs the track-aware adaptive sampler, and
|
||||
then applies a 14-pixel-aligned image budget. The preview shows the exact batch
|
||||
that can be connected to any local or hosted VLM. Three `ViewText` nodes report
|
||||
the selected source indices/timestamps, pixel reduction, and active profile.
|
||||
|
||||
### `moondream3_preview_svg_segment_api.json`
|
||||
|
||||
Runs the official Moondream 3 Preview SVG segmentation skill over
|
||||
`moondream_segment_input.png`. Read the linked model license and change
|
||||
`license_accepted` to `true` before queueing. The graph previews the
|
||||
black/white mask, isolated foreground cutout, and mask/box/polygon overlay;
|
||||
`ViewText` receives the exact native SVG path plus its normalized bbox.
|
||||
|
||||
Moondream's path coordinates are normalized within the returned bbox. The
|
||||
node preserves that path verbatim, safely flattens curves/arcs, applies an
|
||||
even-odd fill for subpath holes, and supersamples the raster edge. The
|
||||
canonical detection keeps both the primary polygon and the full in-process
|
||||
mask.
|
||||
|
||||
### `moondream31_video_detect_api.json`
|
||||
|
||||
Loads `moondream_video_input.mp4`, passes the real frame batch and source FPS
|
||||
to Moondream, and analyzes every frame with four concurrent requests. Photon
|
||||
uses the Loader's `max_batch_size=4` scheduler capacity to form dynamic
|
||||
batches. `ViewText` reports measured throughput and real-time factor. Increase
|
||||
`frame_stride` to 2, 3, or more when full-frame analysis cannot keep up with
|
||||
the source FPS; the canonical results preserve original frame indices and
|
||||
timestamps.
|
||||
|
||||
### `sam2_video_tracking_api.json`
|
||||
|
||||
Runs this bounded pipeline:
|
||||
|
||||
`LoadVideo` → `Video Slice` → `GetVideoComponents` → `ImageScale` →
|
||||
`ImageFromBatch` → Grounding DINO first-frame detection → SAM2.1 propagation.
|
||||
|
||||
The example limits the source to two seconds, scales its largest dimension to
|
||||
768 pixels while preserving aspect ratio, unloads Grounding DINO after
|
||||
seeding, and keeps SAM2.1 video state on CPU. The example requests only the
|
||||
union mask volume; change `mask_output` to `union_and_objects` only when every
|
||||
per-object mask is required. `VLMTrackReport` is an output node and the final
|
||||
`PreviewImage` displays SAM2.1 output index 4.
|
||||
|
||||
For a longer source, change `start_time` and keep a bounded `duration`.
|
||||
Independent slices create independent object-ID sessions.
|
||||
|
||||
### `sam3_core_adapter_blueprint_api.json`
|
||||
|
||||
Uses ComfyUI core nodes to load and run SAM3.1, then passes core
|
||||
`SAM3_TRACK_DATA` through `VLMSAM3TrackAdapter`. The adapter's output 1 is the
|
||||
unchanged core payload consumed by `SAM3_TrackPreview`; output 0 is canonical
|
||||
`VLM_TRACKS` consumed by `VLMTrackReport`.
|
||||
|
||||
The graph intentionally names:
|
||||
|
||||
`ComfyUI/models/checkpoints/sam3.1_multiplex_fp16.safetensors`
|
||||
|
||||
The checkpoint is not bundled. Review the SAM License before downloading
|
||||
[Comfy-Org/sam3.1](https://huggingface.co/Comfy-Org/sam3.1). ComfyUI rejects
|
||||
the graph at prompt validation when the named checkpoint is absent. Use the
|
||||
SAM2.1 example when SAM3.1 access or compatible core support is unavailable.
|
||||
|
||||
## Output history
|
||||
|
||||
ComfyUI returns image/video previews in the execution history and text reports
|
||||
in the output-node UI payload. Canonical JSON is also available on the linked
|
||||
string outputs. Dense masks intentionally stay as tensors rather than being
|
||||
embedded in the JSON report.
|
||||
|
||||
## Creator mask outputs
|
||||
|
||||
`VLM Detections to Masks` preserves its original first three outputs and
|
||||
appends creator-ready derivatives:
|
||||
|
||||
| Index | Output |
|
||||
| ---: | --- |
|
||||
| 0 | Per-frame combined/union `MASK` |
|
||||
| 1 | Flattened per-object `MASK` batch |
|
||||
| 2 | JSON mapping each object mask to its frame/detection/track |
|
||||
| 3 | Per-frame inverse/background `MASK` |
|
||||
| 4 | Combined masks as black-and-white `IMAGE` batches |
|
||||
| 5 | Individual masks as black-and-white `IMAGE` batches |
|
||||
| 6 | Stable-color per-frame instance maps |
|
||||
|
||||
All binary mask values are exactly zero or one. `VLM Mask Processor` can grow,
|
||||
shrink, and feather any of these masks and returns processed, binary, inverse,
|
||||
and black-and-white image outputs. `VLM Mask Composite` accepts the resulting
|
||||
mask plus still-image or video frames and returns a composite, isolated
|
||||
foreground, background-only plate, and mask image. Connect an optional
|
||||
background image/video batch to replace the solid background color.
|
||||
@@ -0,0 +1,45 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadImage",
|
||||
"inputs": {
|
||||
"image": "grounding_input.png"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "VLMOpenVocabularyDetection",
|
||||
"inputs": {
|
||||
"image": [
|
||||
"1",
|
||||
0
|
||||
],
|
||||
"model": "Grounding DINO Tiny (fast)",
|
||||
"labels": "person, dog, bicycle",
|
||||
"box_threshold": 0.3,
|
||||
"text_threshold": 0.25,
|
||||
"max_detections": 100,
|
||||
"fps": 1.0,
|
||||
"nms_threshold": 0.5,
|
||||
"precision": "auto",
|
||||
"batch_size": 1,
|
||||
"unload_after": false
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"2",
|
||||
2
|
||||
]
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"2",
|
||||
1
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,76 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadVideo",
|
||||
"inputs": {
|
||||
"file": "moondream_video_input.mp4"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "GetVideoComponents",
|
||||
"inputs": {
|
||||
"video": [
|
||||
"1",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "Moondream31Loader",
|
||||
"inputs": {
|
||||
"license_accepted": false,
|
||||
"device": "Auto",
|
||||
"max_batch_size": 4,
|
||||
"kv_cache_profile": "Balanced (8K pages)",
|
||||
"model_or_adapter": "moondream3.1-9B-A2B"
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "Moondream31Detect",
|
||||
"inputs": {
|
||||
"model": [
|
||||
"3",
|
||||
0
|
||||
],
|
||||
"image": [
|
||||
"2",
|
||||
0
|
||||
],
|
||||
"object": "person",
|
||||
"fps": [
|
||||
"2",
|
||||
2
|
||||
],
|
||||
"frame_stride": 1,
|
||||
"parallel_requests": 4,
|
||||
"max_objects": 100,
|
||||
"unload_after": false
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"4",
|
||||
2
|
||||
]
|
||||
}
|
||||
},
|
||||
"6": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"4",
|
||||
6
|
||||
]
|
||||
}
|
||||
},
|
||||
"7": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"4",
|
||||
1
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,74 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadImage",
|
||||
"inputs": {
|
||||
"image": "moondream_segment_input.png"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "Moondream31Loader",
|
||||
"inputs": {
|
||||
"license_accepted": false,
|
||||
"device": "Auto",
|
||||
"max_batch_size": 4,
|
||||
"kv_cache_profile": "Balanced (8K pages)",
|
||||
"model_or_adapter": "moondream3-preview"
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "Moondream31Segment",
|
||||
"inputs": {
|
||||
"model": [
|
||||
"2",
|
||||
0
|
||||
],
|
||||
"image": [
|
||||
"1",
|
||||
0
|
||||
],
|
||||
"object": "main foreground object",
|
||||
"fps": 1.0,
|
||||
"frame_stride": 1,
|
||||
"parallel_requests": 1,
|
||||
"svg_supersample": 4,
|
||||
"unload_after": false,
|
||||
"spatial_refs_json": "[]"
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"3",
|
||||
4
|
||||
]
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"3",
|
||||
5
|
||||
]
|
||||
}
|
||||
},
|
||||
"6": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"3",
|
||||
6
|
||||
]
|
||||
}
|
||||
},
|
||||
"7": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"3",
|
||||
2
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,116 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadVideo",
|
||||
"inputs": {
|
||||
"file": "tracking_input.mp4"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "Video Slice",
|
||||
"inputs": {
|
||||
"video": [
|
||||
"1",
|
||||
0
|
||||
],
|
||||
"start_time": 0.0,
|
||||
"duration": 2.0,
|
||||
"strict_duration": false
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "GetVideoComponents",
|
||||
"inputs": {
|
||||
"video": [
|
||||
"2",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "ImageScaleToMaxDimension",
|
||||
"inputs": {
|
||||
"image": [
|
||||
"3",
|
||||
0
|
||||
],
|
||||
"upscale_method": "area",
|
||||
"largest_size": 768
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "ImageFromBatch",
|
||||
"inputs": {
|
||||
"image": [
|
||||
"4",
|
||||
0
|
||||
],
|
||||
"batch_index": 0,
|
||||
"length": 1
|
||||
}
|
||||
},
|
||||
"6": {
|
||||
"class_type": "VLMOpenVocabularyDetection",
|
||||
"inputs": {
|
||||
"image": [
|
||||
"5",
|
||||
0
|
||||
],
|
||||
"model": "Grounding DINO Tiny (fast)",
|
||||
"labels": "person, dog, vehicle",
|
||||
"box_threshold": 0.3,
|
||||
"text_threshold": 0.25,
|
||||
"max_detections": 16,
|
||||
"fps": [
|
||||
"3",
|
||||
2
|
||||
],
|
||||
"nms_threshold": 0.5,
|
||||
"precision": "auto",
|
||||
"batch_size": 1,
|
||||
"unload_after": true
|
||||
}
|
||||
},
|
||||
"7": {
|
||||
"class_type": "VLMSAM2VideoSegmentation",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"4",
|
||||
0
|
||||
],
|
||||
"model": "SAM2.1 Hiera Tiny (fast)",
|
||||
"seed_frame": 0,
|
||||
"fps": [
|
||||
"3",
|
||||
2
|
||||
],
|
||||
"detections": [
|
||||
"6",
|
||||
0
|
||||
],
|
||||
"mask_threshold": 0.0,
|
||||
"precision": "auto",
|
||||
"keep_video_on_cpu": true,
|
||||
"mask_output": "union_only",
|
||||
"render_preview": true,
|
||||
"unload_after": false
|
||||
}
|
||||
},
|
||||
"8": {
|
||||
"class_type": "VLMTrackReport",
|
||||
"inputs": {
|
||||
"tracks": [
|
||||
"7",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"9": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"7",
|
||||
4
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,116 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadVideo",
|
||||
"inputs": {
|
||||
"file": "tracking_input.mp4"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "Video Slice",
|
||||
"inputs": {
|
||||
"video": [
|
||||
"1",
|
||||
0
|
||||
],
|
||||
"start_time": 0.0,
|
||||
"duration": 2.0,
|
||||
"strict_duration": false
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "GetVideoComponents",
|
||||
"inputs": {
|
||||
"video": [
|
||||
"2",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "ImageScaleToMaxDimension",
|
||||
"inputs": {
|
||||
"image": [
|
||||
"3",
|
||||
0
|
||||
],
|
||||
"upscale_method": "area",
|
||||
"largest_size": 768
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "CheckpointLoaderSimple",
|
||||
"inputs": {
|
||||
"ckpt_name": "sam3.1_multiplex_fp16.safetensors"
|
||||
}
|
||||
},
|
||||
"6": {
|
||||
"class_type": "CLIPTextEncode",
|
||||
"inputs": {
|
||||
"text": "person, dog, vehicle",
|
||||
"clip": [
|
||||
"5",
|
||||
1
|
||||
]
|
||||
}
|
||||
},
|
||||
"7": {
|
||||
"class_type": "SAM3_VideoTrack",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"4",
|
||||
0
|
||||
],
|
||||
"model": [
|
||||
"5",
|
||||
0
|
||||
],
|
||||
"conditioning": [
|
||||
"6",
|
||||
0
|
||||
],
|
||||
"detection_threshold": 0.5,
|
||||
"max_objects": 8,
|
||||
"detect_interval": 1
|
||||
}
|
||||
},
|
||||
"8": {
|
||||
"class_type": "VLMSAM3TrackAdapter",
|
||||
"inputs": {
|
||||
"track_data": [
|
||||
"7",
|
||||
0
|
||||
],
|
||||
"fps": [
|
||||
"3",
|
||||
2
|
||||
]
|
||||
}
|
||||
},
|
||||
"9": {
|
||||
"class_type": "VLMTrackReport",
|
||||
"inputs": {
|
||||
"tracks": [
|
||||
"8",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"10": {
|
||||
"class_type": "SAM3_TrackPreview",
|
||||
"inputs": {
|
||||
"track_data": [
|
||||
"8",
|
||||
1
|
||||
],
|
||||
"images": [
|
||||
"4",
|
||||
0
|
||||
],
|
||||
"opacity": 0.5,
|
||||
"fps": [
|
||||
"3",
|
||||
2
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,91 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadVideo",
|
||||
"inputs": {
|
||||
"file": "video_understanding_input.mp4"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "GetVideoComponents",
|
||||
"inputs": {
|
||||
"video": [
|
||||
"1",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "VLMVideoTemporalReasoner",
|
||||
"inputs": {
|
||||
"frames": [
|
||||
"2",
|
||||
0
|
||||
],
|
||||
"fps": [
|
||||
"2",
|
||||
2
|
||||
],
|
||||
"task": "Detailed temporal summary",
|
||||
"question": "Describe what happens over time and identify the visible evidence.",
|
||||
"model": "Qwen 3 VL 2B Instruct",
|
||||
"custom_model_id": "",
|
||||
"memory_mode": "ComfyUI managed (BF16)",
|
||||
"max_frames": 16,
|
||||
"max_events": 24,
|
||||
"max_new_tokens": 768,
|
||||
"strategy": "Hybrid: scene + motion + tracks",
|
||||
"minimum_gap_seconds": 0.15,
|
||||
"analysis_max_side": 448,
|
||||
"attention_mode": "Auto (SDPA)",
|
||||
"enable_thinking": false,
|
||||
"strict_output": true,
|
||||
"unload_after": false,
|
||||
"stream_output": true
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"3",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"3",
|
||||
6
|
||||
]
|
||||
}
|
||||
},
|
||||
"6": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"3",
|
||||
7
|
||||
]
|
||||
}
|
||||
},
|
||||
"7": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"3",
|
||||
5
|
||||
]
|
||||
}
|
||||
},
|
||||
"8": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"3",
|
||||
3
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,98 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadVideo",
|
||||
"inputs": {
|
||||
"file": "vlm_api_people_birds.mp4"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "GetVideoComponents",
|
||||
"inputs": {
|
||||
"video": [
|
||||
"1",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "VLMPerformanceProfile",
|
||||
"inputs": {
|
||||
"profile": "Fast video"
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "VLMAdaptiveFrameSampler",
|
||||
"inputs": {
|
||||
"frames": [
|
||||
"2",
|
||||
0
|
||||
],
|
||||
"fps": [
|
||||
"2",
|
||||
2
|
||||
],
|
||||
"max_frames": [
|
||||
"3",
|
||||
0
|
||||
],
|
||||
"strategy": "Hybrid: scene + motion + tracks",
|
||||
"minimum_gap_seconds": 0.15,
|
||||
"thumbnail_size": 96
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "VLMImagePixelBudget",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"4",
|
||||
0
|
||||
],
|
||||
"max_megapixels": [
|
||||
"3",
|
||||
1
|
||||
],
|
||||
"max_edge": [
|
||||
"3",
|
||||
2
|
||||
],
|
||||
"multiple": "14",
|
||||
"resize_quality": "Fast (area)"
|
||||
}
|
||||
},
|
||||
"6": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"5",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"7": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"4",
|
||||
3
|
||||
]
|
||||
}
|
||||
},
|
||||
"8": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"5",
|
||||
3
|
||||
]
|
||||
}
|
||||
},
|
||||
"9": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"3",
|
||||
5
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
-314
@@ -1,314 +0,0 @@
|
||||
import os
|
||||
import json
|
||||
import shutil
|
||||
from os.path import join, dirname, abspath, exists
|
||||
from os import makedirs, symlink, readlink
|
||||
import platform
|
||||
import subprocess
|
||||
import sys
|
||||
import importlib.util
|
||||
import re
|
||||
import torch
|
||||
import cpuinfo
|
||||
import packaging.tags
|
||||
from requests import get
|
||||
import asyncio
|
||||
import inspect
|
||||
import aiohttp
|
||||
from server import PromptServer
|
||||
from tqdm import tqdm
|
||||
import pkg_resources
|
||||
|
||||
|
||||
|
||||
def get_python_version():
|
||||
"""Return the Python version in a concise format, e.g., '39' for Python 3.9."""
|
||||
version_match = re.match(r"3\.(\d+)", platform.python_version())
|
||||
if version_match:
|
||||
return "3" + version_match.group(1)
|
||||
else:
|
||||
return None
|
||||
|
||||
def get_system_info():
|
||||
"""Gather system information related to NVIDIA GPU, CUDA version, AVX2 support, Python version, OS, and platform tag."""
|
||||
system_info = {
|
||||
'gpu': False,
|
||||
'cuda_version': None,
|
||||
'avx2': False,
|
||||
'python_version': get_python_version(),
|
||||
'os': platform.system(),
|
||||
'os_bit': platform.architecture()[0].replace("bit", ""),
|
||||
'platform_tag': None,
|
||||
}
|
||||
|
||||
# Check for NVIDIA GPU and CUDA version
|
||||
if importlib.util.find_spec('torch'):
|
||||
system_info['gpu'] = torch.cuda.is_available()
|
||||
if system_info['gpu']:
|
||||
system_info['cuda_version'] = "cu" + torch.version.cuda.replace(".", "").strip()
|
||||
|
||||
# Check for AVX2 support
|
||||
if importlib.util.find_spec('cpuinfo'):
|
||||
system_info['avx2'] = 'avx2' in cpuinfo.get_cpu_info()['flags']
|
||||
|
||||
# Determine the platform tag
|
||||
if importlib.util.find_spec('packaging.tags'):
|
||||
system_info['platform_tag'] = next(packaging.tags.sys_tags()).platform
|
||||
|
||||
return system_info
|
||||
|
||||
def latest_lamacpp():
|
||||
try:
|
||||
response = get("https://api.github.com/repos/abetlen/llama-cpp-python/releases/latest")
|
||||
return response.json()["tag_name"].replace("v", "")
|
||||
except Exception:
|
||||
return "0.2.20"
|
||||
|
||||
def install_package(package_name, custom_command=None):
|
||||
if not package_is_installed(package_name):
|
||||
print(f"Installing {package_name}...")
|
||||
command = [sys.executable, "-m", "pip", "install", package_name, "--no-cache-dir"]
|
||||
if custom_command:
|
||||
command += custom_command.split()
|
||||
subprocess.check_call(command)
|
||||
else:
|
||||
print(f"{package_name} is already installed.")
|
||||
|
||||
def package_is_installed(package_name):
|
||||
return importlib.util.find_spec(package_name) is not None
|
||||
|
||||
def install_llama(system_info):
|
||||
imported = package_is_installed("llama-cpp-python") or package_is_installed("llama_cpp")
|
||||
if imported:
|
||||
print("llama-cpp installed")
|
||||
else:
|
||||
lcpp_version = latest_lamacpp()
|
||||
base_url = "https://github.com/abetlen/llama-cpp-python/releases/download/v"
|
||||
avx = "AVX2" if system_info['avx2'] else "AVX"
|
||||
if system_info['gpu']:
|
||||
cuda_version = system_info['cuda_version']
|
||||
custom_command = f"--force-reinstall --no-deps --index-url=https://jllllll.github.io/llama-cpp-python-cuBLAS-wheels/{avx}/{cuda_version}"
|
||||
else:
|
||||
custom_command = f"{base_url}{lcpp_version}/llama_cpp_python-{lcpp_version}-{system_info['platform_tag']}.whl"
|
||||
install_package("llama-cpp-python", custom_command=custom_command)
|
||||
|
||||
def install_autogptq(system_info):
|
||||
# Check OS compatibility
|
||||
imported = package_is_installed("auto_gptq")
|
||||
if imported:
|
||||
print("AutoGPTQ installed")
|
||||
else:
|
||||
if system_info['os'] not in ['Linux', 'Windows']:
|
||||
print("AutoGPTQ is not supported on your operating system.")
|
||||
return
|
||||
|
||||
# Prepare base install command
|
||||
base_command = [sys.executable, "-m", "pip", "install", "auto-gptq"]
|
||||
|
||||
# Determine the specific install command based on GPU and CUDA/ROCm version
|
||||
if system_info['gpu']:
|
||||
if 'cuda_version' in system_info and system_info['cuda_version'] in ['cu118', 'cu121']:
|
||||
if system_info['cuda_version'] == 'cu118':
|
||||
base_command += ["--extra-index-url", "https://huggingface.github.io/autogptq-index/whl/cu118/"]
|
||||
# No extra URL needed for cu121 as it's the default
|
||||
elif 'rocm_version' in system_info and system_info['rocm_version'] == 'rocm573':
|
||||
base_command += ["--extra-index-url", "https://huggingface.github.io/autogptq-index/whl/rocm573/"]
|
||||
else:
|
||||
print("Unsupported GPU configuration for AutoGPTQ.")
|
||||
return
|
||||
else:
|
||||
print("No GPU detected. AutoGPTQ installation requires a GPU with CUDA or ROCm support.")
|
||||
return
|
||||
|
||||
# Execute the installation command
|
||||
try:
|
||||
print(f"Installing AutoGPTQ with command: {' '.join(base_command)}")
|
||||
subprocess.check_call(base_command)
|
||||
except Exception as e:
|
||||
print(f"Failed to install AutoGPTQ: {e}")
|
||||
|
||||
config = None
|
||||
|
||||
def is_logging_enabled():
|
||||
config = get_extension_config()
|
||||
if "logging" not in config:
|
||||
return False
|
||||
return config["logging"]
|
||||
|
||||
def log(message, type=None, always=False, name=None):
|
||||
if not always and not is_logging_enabled():
|
||||
return
|
||||
|
||||
if type is not None:
|
||||
message = f"[{type}] {message}"
|
||||
|
||||
if name is None:
|
||||
name = get_extension_config()["name"]
|
||||
|
||||
print(f"(vlmnodes:{name}) {message}")
|
||||
|
||||
def get_ext_dir(subpath=None, mkdir=False):
|
||||
dir = os.path.dirname(__file__)
|
||||
if subpath is not None:
|
||||
dir = os.path.join(dir, subpath)
|
||||
|
||||
dir = os.path.abspath(dir)
|
||||
|
||||
if mkdir and not os.path.exists(dir):
|
||||
os.makedirs(dir)
|
||||
return dir
|
||||
|
||||
def get_comfy_dir(subpath=None, mkdir=False):
|
||||
dir = os.path.dirname(inspect.getfile(PromptServer))
|
||||
if subpath is not None:
|
||||
dir = os.path.join(dir, subpath)
|
||||
|
||||
dir = os.path.abspath(dir)
|
||||
|
||||
if mkdir and not os.path.exists(dir):
|
||||
os.makedirs(dir)
|
||||
return dir
|
||||
|
||||
def get_web_ext_dir():
|
||||
config = get_extension_config()
|
||||
name = config["name"]
|
||||
dir = get_comfy_dir("web/extensions/vlmnodes")
|
||||
if not os.path.exists(dir):
|
||||
os.makedirs(dir)
|
||||
dir = os.path.join(dir, name)
|
||||
return dir
|
||||
|
||||
def get_extension_config(reload=False):
|
||||
global config
|
||||
if reload == False and config is not None:
|
||||
return config
|
||||
|
||||
config_path = get_ext_dir("vlmnodes.json")
|
||||
if not os.path.exists(config_path):
|
||||
log("Missing vlmnodes.json, this extension may not work correctly. Please reinstall the extension.",
|
||||
type="ERROR", always=True, name="???")
|
||||
print(f"Extension path: {get_ext_dir()}")
|
||||
return {"name": "Unknown", "version": -1}
|
||||
with open(config_path, "r") as f:
|
||||
config = json.loads(f.read())
|
||||
return config
|
||||
|
||||
def link_js(src, dst):
|
||||
src = os.path.abspath(src)
|
||||
dst = os.path.abspath(dst)
|
||||
if os.name == "nt":
|
||||
try:
|
||||
import _winapi
|
||||
_winapi.CreateJunction(src, dst)
|
||||
return True
|
||||
except:
|
||||
pass
|
||||
try:
|
||||
os.symlink(src, dst)
|
||||
return True
|
||||
except:
|
||||
import logging
|
||||
logging.exception('')
|
||||
return False
|
||||
|
||||
def is_junction(path):
|
||||
if os.name != "nt":
|
||||
return False
|
||||
try:
|
||||
return bool(os.readlink(path))
|
||||
except OSError:
|
||||
return False
|
||||
|
||||
def install_js():
|
||||
src_dir = get_ext_dir("js")
|
||||
if not os.path.exists(src_dir):
|
||||
log("No JS")
|
||||
return
|
||||
|
||||
dst_dir = get_web_ext_dir()
|
||||
|
||||
if os.path.exists(dst_dir):
|
||||
if os.path.islink(dst_dir) or is_junction(dst_dir):
|
||||
log("JS already linked")
|
||||
return
|
||||
elif link_js(src_dir, dst_dir):
|
||||
log("JS linked")
|
||||
return
|
||||
|
||||
log("Copying JS files")
|
||||
shutil.copytree(src_dir, dst_dir, dirs_exist_ok=True)
|
||||
|
||||
def init(check_imports=None):
|
||||
log("Init")
|
||||
|
||||
if check_imports is not None:
|
||||
import importlib.util
|
||||
for imp in check_imports:
|
||||
spec = importlib.util.find_spec(imp)
|
||||
if spec is None:
|
||||
log(f"{imp} is required, please check requirements are installed.",
|
||||
type="ERROR", always=True)
|
||||
return False
|
||||
|
||||
install_js()
|
||||
return True
|
||||
|
||||
def get_async_loop():
|
||||
loop = None
|
||||
try:
|
||||
loop = asyncio.get_event_loop()
|
||||
except:
|
||||
loop = asyncio.new_event_loop()
|
||||
asyncio.set_event_loop(loop)
|
||||
return loop
|
||||
|
||||
def get_http_session():
|
||||
loop = get_async_loop()
|
||||
return aiohttp.ClientSession(loop=loop)
|
||||
|
||||
async def download(url, stream, update_callback=None, session=None):
|
||||
close_session = False
|
||||
if session is None:
|
||||
close_session = True
|
||||
session = get_http_session()
|
||||
try:
|
||||
async with session.get(url) as response:
|
||||
size = int(response.headers.get('content-length', 0)) or None
|
||||
|
||||
with tqdm(
|
||||
unit='B', unit_scale=True, miniters=1, desc=url.split('/')[-1], total=size,
|
||||
) as progressbar:
|
||||
perc = 0
|
||||
async for chunk in response.content.iter_chunked(2048):
|
||||
stream.write(chunk)
|
||||
progressbar.update(len(chunk))
|
||||
if update_callback is not None and progressbar.total is not None and progressbar.total != 0:
|
||||
last = perc
|
||||
perc = round(progressbar.n / progressbar.total, 2)
|
||||
if perc != last:
|
||||
last = perc
|
||||
await update_callback(perc)
|
||||
finally:
|
||||
if close_session and session is not None:
|
||||
await session.close()
|
||||
|
||||
async def download_to_file(url, destination, update_callback=None, is_ext_subpath=True, session=None):
|
||||
if is_ext_subpath:
|
||||
destination = get_ext_dir(destination)
|
||||
with open(destination, mode='wb') as f:
|
||||
download(url, f, update_callback, session)
|
||||
|
||||
def is_inside_dir(root_dir, check_path):
|
||||
root_dir = os.path.abspath(root_dir)
|
||||
if not os.path.isabs(check_path):
|
||||
check_path = os.path.abspath(os.path.join(root_dir, check_path))
|
||||
return os.path.commonpath([check_path, root_dir]) == root_dir
|
||||
|
||||
def get_child_dir(root_dir, child_path, throw_if_outside=True):
|
||||
child_path = os.path.abspath(os.path.join(root_dir, child_path))
|
||||
if is_inside_dir(root_dir, child_path):
|
||||
return child_path
|
||||
if throw_if_outside:
|
||||
raise NotADirectoryError(
|
||||
"Saving outside the target folder is not allowed.")
|
||||
return None
|
||||
@@ -1,42 +0,0 @@
|
||||
import { app } from "/scripts/app.js";
|
||||
import { ComfyWidgets } from "/scripts/widgets.js";
|
||||
|
||||
app.registerExtension({
|
||||
name: "n.JsonToText",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData, app) {
|
||||
|
||||
if (nodeData.name === "JsonToText") {
|
||||
console.warn("JsonToText");
|
||||
|
||||
const onExecuted = nodeType.prototype.onExecuted;
|
||||
|
||||
nodeType.prototype.onExecuted = function (message) {
|
||||
if (this.widgets) {
|
||||
for (let i = 1; i < this.widgets.length; i++) {
|
||||
this.widgets[i].onRemove?.();
|
||||
}
|
||||
this.widgets.length = 1;
|
||||
}
|
||||
|
||||
// Call the original onExecuted method if it exists.
|
||||
onExecuted?.apply(this, arguments);
|
||||
|
||||
// Check if the "text" widget already exists.
|
||||
let textWidget = this.widgets.find(w => w.name === "newtext");
|
||||
if (!textWidget) {
|
||||
// If the "text" widget does not exist, create it.
|
||||
textWidget = ComfyWidgets["STRING"](this, "newtext", ["STRING", { multiline: true }], app).widget;
|
||||
}
|
||||
|
||||
// Generate a random number and set it as the value of the "text" widget.
|
||||
|
||||
textWidget.inputEl.readOnly = true;
|
||||
textWidget.inputEl.style.opacity = 0.6;
|
||||
textWidget.value = message["text"].join("");
|
||||
// change color of the widget
|
||||
console.log(message)
|
||||
|
||||
};
|
||||
}
|
||||
},
|
||||
});
|
||||
@@ -1,42 +0,0 @@
|
||||
import { app } from "/scripts/app.js";
|
||||
import { ComfyWidgets } from "/scripts/widgets.js";
|
||||
|
||||
app.registerExtension({
|
||||
name: "n.ViewText",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData, app) {
|
||||
|
||||
if (nodeData.name === "ViewText") {
|
||||
console.warn("ViewText");
|
||||
|
||||
const onExecuted = nodeType.prototype.onExecuted;
|
||||
|
||||
nodeType.prototype.onExecuted = function (message) {
|
||||
if (this.widgets) {
|
||||
for (let i = 1; i < this.widgets.length; i++) {
|
||||
this.widgets[i].onRemove?.();
|
||||
}
|
||||
this.widgets.length = 1;
|
||||
}
|
||||
|
||||
// Call the original onExecuted method if it exists.
|
||||
onExecuted?.apply(this, arguments);
|
||||
|
||||
// Check if the "text" widget already exists.
|
||||
let textWidget = this.widgets.find(w => w.name === "new_text");
|
||||
if (!textWidget) {
|
||||
// If the "text" widget does not exist, create it.
|
||||
textWidget = ComfyWidgets["STRING"](this, "new_text", ["STRING", { multiline: true }], app).widget;
|
||||
}
|
||||
|
||||
// Generate a random number and set it as the value of the "text" widget.
|
||||
|
||||
textWidget.inputEl.readOnly = true;
|
||||
textWidget.inputEl.style.opacity = 0.6;
|
||||
textWidget.value = message["text"].join("");
|
||||
// change color of the widget
|
||||
console.log(message)
|
||||
|
||||
};
|
||||
}
|
||||
},
|
||||
});
|
||||
@@ -0,0 +1,280 @@
|
||||
"""Model-agnostic acceleration utilities for image and video VLM workflows.
|
||||
|
||||
These nodes reduce visual work *before* it reaches a model. They are therefore
|
||||
portable across Transformers, llama.cpp, Photon, hosted APIs, CUDA, ROCm, MPS,
|
||||
XPU, and CPU runtimes. No model is downloaded and no global PyTorch setting is
|
||||
changed when this module is imported or executed.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import math
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as functional
|
||||
|
||||
|
||||
RESIZE_QUALITY = (
|
||||
"Fast (area)",
|
||||
"Quality (bicubic)",
|
||||
)
|
||||
PERFORMANCE_PROFILES = {
|
||||
"Live / robotics": {
|
||||
"max_frames": 24,
|
||||
"max_megapixels": 0.5,
|
||||
"max_edge": 896,
|
||||
"batch_size": 8,
|
||||
"unload_after": False,
|
||||
},
|
||||
"Fast video": {
|
||||
"max_frames": 48,
|
||||
"max_megapixels": 0.75,
|
||||
"max_edge": 1024,
|
||||
"batch_size": 8,
|
||||
"unload_after": False,
|
||||
},
|
||||
"Balanced": {
|
||||
"max_frames": 64,
|
||||
"max_megapixels": 1.0,
|
||||
"max_edge": 1344,
|
||||
"batch_size": 4,
|
||||
"unload_after": False,
|
||||
},
|
||||
"High detail": {
|
||||
"max_frames": 96,
|
||||
"max_megapixels": 2.0,
|
||||
"max_edge": 2048,
|
||||
"batch_size": 2,
|
||||
"unload_after": False,
|
||||
},
|
||||
"Low VRAM handoff": {
|
||||
"max_frames": 32,
|
||||
"max_megapixels": 0.75,
|
||||
"max_edge": 1024,
|
||||
"batch_size": 1,
|
||||
"unload_after": True,
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
def _json(value: Any) -> str:
|
||||
return json.dumps(
|
||||
value,
|
||||
ensure_ascii=False,
|
||||
allow_nan=False,
|
||||
sort_keys=True,
|
||||
indent=2,
|
||||
)
|
||||
|
||||
|
||||
def _validate_image_batch(images: torch.Tensor) -> tuple[torch.Tensor, bool]:
|
||||
if not isinstance(images, torch.Tensor):
|
||||
raise TypeError("images must be a ComfyUI IMAGE tensor.")
|
||||
single = images.ndim == 3
|
||||
value = images.unsqueeze(0) if single else images
|
||||
if value.ndim != 4:
|
||||
raise ValueError(
|
||||
f"Expected an HWC/BHWC or CHW/BCHW IMAGE tensor, got {tuple(images.shape)}."
|
||||
)
|
||||
if value.shape[-1] in (1, 3, 4):
|
||||
return value, single
|
||||
if value.shape[1] in (1, 3, 4):
|
||||
return value.permute(0, 2, 3, 1), single
|
||||
raise ValueError(f"Unsupported image channel shape: {tuple(images.shape)}.")
|
||||
|
||||
|
||||
def optimize_image_pixels(
|
||||
images: torch.Tensor,
|
||||
*,
|
||||
max_megapixels: float,
|
||||
max_edge: int,
|
||||
multiple: int,
|
||||
resize_quality: str,
|
||||
) -> tuple[torch.Tensor, dict[str, Any]]:
|
||||
"""Downscale a batch once to a bounded visual-token pixel budget."""
|
||||
|
||||
value, single = _validate_image_batch(images)
|
||||
if not math.isfinite(float(max_megapixels)) or max_megapixels <= 0:
|
||||
raise ValueError("max_megapixels must be finite and positive.")
|
||||
if not isinstance(max_edge, int) or max_edge < 32:
|
||||
raise ValueError("max_edge must be at least 32 pixels.")
|
||||
if multiple not in {1, 14, 28, 32}:
|
||||
raise ValueError("multiple must be one of 1, 14, 28, or 32.")
|
||||
if resize_quality not in RESIZE_QUALITY:
|
||||
raise ValueError(f"Unknown resize quality {resize_quality!r}.")
|
||||
|
||||
height, width = int(value.shape[1]), int(value.shape[2])
|
||||
pixel_budget = float(max_megapixels) * 1_000_000
|
||||
scale = min(
|
||||
1.0,
|
||||
float(max_edge) / max(width, height),
|
||||
math.sqrt(pixel_budget / (width * height)),
|
||||
)
|
||||
|
||||
def bounded_dimension(dimension: int) -> int:
|
||||
target = max(1, math.floor(dimension * scale))
|
||||
if multiple == 1 or target < multiple:
|
||||
return target
|
||||
return max(multiple, (target // multiple) * multiple)
|
||||
|
||||
output_width = bounded_dimension(width)
|
||||
output_height = bounded_dimension(height)
|
||||
output = value
|
||||
resized_image = (output_height, output_width) != (height, width)
|
||||
if resized_image:
|
||||
nchw = value.permute(0, 3, 1, 2)
|
||||
if resize_quality == "Fast (area)":
|
||||
resized = functional.interpolate(
|
||||
nchw,
|
||||
size=(output_height, output_width),
|
||||
mode="area",
|
||||
)
|
||||
else:
|
||||
resized = functional.interpolate(
|
||||
nchw,
|
||||
size=(output_height, output_width),
|
||||
mode="bicubic",
|
||||
align_corners=False,
|
||||
antialias=True,
|
||||
)
|
||||
output = resized.permute(0, 2, 3, 1).clamp(0.0, 1.0)
|
||||
report = {
|
||||
"frames": int(value.shape[0]),
|
||||
"input_width": width,
|
||||
"input_height": height,
|
||||
"output_width": output_width,
|
||||
"output_height": output_height,
|
||||
"input_pixels_per_frame": width * height,
|
||||
"output_pixels_per_frame": output_width * output_height,
|
||||
"visual_work_reduction": (
|
||||
(width * height) / max(1, output_width * output_height)
|
||||
),
|
||||
"resized": resized_image,
|
||||
"multiple": multiple,
|
||||
"quality": resize_quality,
|
||||
}
|
||||
if not resized_image:
|
||||
return images, report
|
||||
return (output[0] if single else output), report
|
||||
|
||||
|
||||
class VLMPerformanceProfile:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"profile": (
|
||||
tuple(PERFORMANCE_PROFILES),
|
||||
{"default": "Balanced"},
|
||||
)
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("INT", "FLOAT", "INT", "INT", "BOOLEAN", "STRING")
|
||||
RETURN_NAMES = (
|
||||
"max_frames",
|
||||
"max_megapixels",
|
||||
"max_edge",
|
||||
"batch_size",
|
||||
"unload_after",
|
||||
"profile_json",
|
||||
)
|
||||
FUNCTION = "profile"
|
||||
CATEGORY = "VLM Nodes/Performance"
|
||||
DESCRIPTION = (
|
||||
"Portable speed/quality presets for the sampler, pixel optimizer, "
|
||||
"and VLM batch inputs. The profile never changes global runtime state."
|
||||
)
|
||||
|
||||
def profile(self, profile):
|
||||
values = dict(PERFORMANCE_PROFILES[profile])
|
||||
values["profile"] = profile
|
||||
return (
|
||||
values["max_frames"],
|
||||
values["max_megapixels"],
|
||||
values["max_edge"],
|
||||
values["batch_size"],
|
||||
values["unload_after"],
|
||||
_json(values),
|
||||
)
|
||||
|
||||
|
||||
class VLMImagePixelBudget:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"images": ("IMAGE",),
|
||||
"max_megapixels": (
|
||||
"FLOAT",
|
||||
{"default": 1.0, "min": 0.01, "max": 64.0, "step": 0.05},
|
||||
),
|
||||
"max_edge": (
|
||||
"INT",
|
||||
{"default": 1344, "min": 32, "max": 16384, "step": 14},
|
||||
),
|
||||
"multiple": (
|
||||
("1", "14", "28", "32"),
|
||||
{
|
||||
"default": "14",
|
||||
"tooltip": (
|
||||
"14/28 suit common VLM vision patches; 32 suits "
|
||||
"many detector backbones. Use 1 for arbitrary sizes."
|
||||
),
|
||||
},
|
||||
),
|
||||
"resize_quality": (
|
||||
RESIZE_QUALITY,
|
||||
{"default": "Fast (area)"},
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE", "INT", "INT", "STRING")
|
||||
RETURN_NAMES = (
|
||||
"optimized_images",
|
||||
"width",
|
||||
"height",
|
||||
"optimization_report",
|
||||
)
|
||||
FUNCTION = "optimize"
|
||||
CATEGORY = "VLM Nodes/Performance"
|
||||
DESCRIPTION = (
|
||||
"Apply one portable pixel budget before any VLM, avoiding repeated "
|
||||
"high-resolution visual-token work while preserving aspect ratio."
|
||||
)
|
||||
|
||||
def optimize(
|
||||
self,
|
||||
images,
|
||||
max_megapixels,
|
||||
max_edge,
|
||||
multiple,
|
||||
resize_quality,
|
||||
):
|
||||
output, report = optimize_image_pixels(
|
||||
images,
|
||||
max_megapixels=float(max_megapixels),
|
||||
max_edge=int(max_edge),
|
||||
multiple=int(multiple),
|
||||
resize_quality=resize_quality,
|
||||
)
|
||||
return (
|
||||
output,
|
||||
report["output_width"],
|
||||
report["output_height"],
|
||||
_json(report),
|
||||
)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"VLMPerformanceProfile": VLMPerformanceProfile,
|
||||
"VLMImagePixelBudget": VLMImagePixelBudget,
|
||||
}
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"VLMPerformanceProfile": "VLM Performance Profile",
|
||||
"VLMImagePixelBudget": "VLM Image Pixel Budget",
|
||||
}
|
||||
@@ -0,0 +1,231 @@
|
||||
"""Lazy AudioLDM2 generation with legacy and standard ComfyUI AUDIO outputs."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
import folder_paths
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
execution_device,
|
||||
require_module,
|
||||
reserve_external_vram,
|
||||
snapshot_download,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
|
||||
class AnyType(str):
|
||||
def __ne__(self, other):
|
||||
return False
|
||||
|
||||
|
||||
ANY = AnyType("*")
|
||||
|
||||
|
||||
class AudioLDM2Predictor:
|
||||
def __init__(self, cpu_offload=True):
|
||||
diffusers = require_module("diffusers")
|
||||
path = snapshot_download(
|
||||
"cvssp/audioldm2",
|
||||
"audioldm2",
|
||||
ignore_patterns=["*.bin", "*.jpg", "*.png"],
|
||||
)
|
||||
self.device = execution_device()
|
||||
dtype = torch_dtype("float16", self.device)
|
||||
if self.device.type != "cpu":
|
||||
reserve_external_vram(8 * 1024**3)
|
||||
self.pipeline = diffusers.AudioLDM2Pipeline.from_pretrained(
|
||||
path, torch_dtype=dtype
|
||||
)
|
||||
# Accelerate's model CPU offload is currently reliable on the CUDA API,
|
||||
# which covers both NVIDIA CUDA and AMD ROCm PyTorch builds.
|
||||
if self.device.type == "cuda" and cpu_offload:
|
||||
require_module("accelerate")
|
||||
self.pipeline.enable_model_cpu_offload()
|
||||
else:
|
||||
self.pipeline.to(self.device)
|
||||
|
||||
def close(self):
|
||||
self.pipeline = None
|
||||
import gc
|
||||
|
||||
gc.collect()
|
||||
try:
|
||||
import comfy.model_management as model_management
|
||||
|
||||
model_management.soft_empty_cache()
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
def generate(self, text, negative, duration, guidance, seed, count, steps):
|
||||
# MPS generators are not supported by every PyTorch/Diffusers pairing.
|
||||
# A CPU generator remains deterministic and works with every pipeline.
|
||||
generator_device = (
|
||||
self.device if self.device.type in {"cuda", "xpu"} else "cpu"
|
||||
)
|
||||
generator = torch.Generator(device=generator_device).manual_seed(
|
||||
int(seed)
|
||||
)
|
||||
audios = self.pipeline(
|
||||
text,
|
||||
negative_prompt=negative or None,
|
||||
audio_length_in_s=float(duration),
|
||||
guidance_scale=float(guidance),
|
||||
num_inference_steps=int(steps),
|
||||
num_waveforms_per_prompt=int(count),
|
||||
generator=generator,
|
||||
).audios
|
||||
array = np.asarray(audios, dtype=np.float32)
|
||||
if array.ndim == 1:
|
||||
array = array[None, :]
|
||||
native_rate = int(
|
||||
getattr(
|
||||
getattr(getattr(self.pipeline, "vae", None), "config", None),
|
||||
"sampling_rate",
|
||||
16000,
|
||||
)
|
||||
)
|
||||
return array, native_rate
|
||||
|
||||
|
||||
class AudioLDM2Node(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"text": ("STRING", {"default": "", "multiline": True}),
|
||||
"negative_prompt": (
|
||||
"STRING",
|
||||
{"default": "", "multiline": True},
|
||||
),
|
||||
"duration": (
|
||||
"INT",
|
||||
{"default": 10, "min": 1, "max": 60},
|
||||
),
|
||||
"guidance_scale": (
|
||||
"FLOAT",
|
||||
{"default": 3.5, "min": 0.1, "max": 20.0, "step": 0.1},
|
||||
),
|
||||
"seed": ("INT", {"default": 42, "min": 0}),
|
||||
"n_candidates": (
|
||||
"INT",
|
||||
{"default": 1, "min": 1, "max": 10},
|
||||
),
|
||||
"sample_rate": (
|
||||
"INT",
|
||||
{"default": 16000, "min": 8000, "max": 48000},
|
||||
),
|
||||
"extension": (["wav", "flac"],),
|
||||
},
|
||||
"optional": {
|
||||
"steps": ("INT", {"default": 100, "min": 10, "max": 500}),
|
||||
"cpu_offload": ("BOOLEAN", {"default": True}),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_NAMES = ("wave_form", "sample_rate", "audio")
|
||||
RETURN_TYPES = (ANY, "INT", "AUDIO")
|
||||
OUTPUT_NODE = True
|
||||
FUNCTION = "generate_audio_final"
|
||||
CATEGORY = "VLM Nodes/Audio"
|
||||
|
||||
def generate_audio_final(
|
||||
self,
|
||||
text,
|
||||
negative_prompt,
|
||||
duration,
|
||||
guidance_scale,
|
||||
sample_rate,
|
||||
seed,
|
||||
n_candidates,
|
||||
extension,
|
||||
steps=100,
|
||||
cpu_offload=True,
|
||||
unload_after=False,
|
||||
):
|
||||
del extension
|
||||
predictor = self.get_or_create_model(
|
||||
("audioldm2", bool(cpu_offload)),
|
||||
lambda: AudioLDM2Predictor(cpu_offload),
|
||||
)
|
||||
try:
|
||||
waveforms, native_rate = predictor.generate(
|
||||
text,
|
||||
negative_prompt,
|
||||
duration,
|
||||
guidance_scale,
|
||||
seed,
|
||||
n_candidates,
|
||||
steps,
|
||||
)
|
||||
if int(sample_rate) != native_rate:
|
||||
samples = torch.from_numpy(waveforms).unsqueeze(1)
|
||||
target_length = round(
|
||||
samples.shape[-1] * int(sample_rate) / native_rate
|
||||
)
|
||||
waveforms = (
|
||||
torch.nn.functional.interpolate(
|
||||
samples,
|
||||
size=target_length,
|
||||
mode="linear",
|
||||
align_corners=False,
|
||||
)
|
||||
.squeeze(1)
|
||||
.numpy()
|
||||
)
|
||||
# Standard Comfy AUDIO is [batch, channels, samples].
|
||||
audio = {
|
||||
"waveform": torch.from_numpy(waveforms).unsqueeze(1),
|
||||
"sample_rate": int(sample_rate),
|
||||
}
|
||||
return (waveforms[0].tolist(), int(sample_rate), audio)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
class SaveAudioNode:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"waveforms": (ANY,),
|
||||
"sample_rate": ("INT",),
|
||||
"extension": (["wav", "flac"],),
|
||||
"filename": ("STRING", {"default": "audio"}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ()
|
||||
FUNCTION = "save_audio"
|
||||
CATEGORY = "VLM Nodes/Audio"
|
||||
OUTPUT_NODE = True
|
||||
|
||||
def save_audio(self, waveforms, sample_rate, extension, filename):
|
||||
soundfile = require_module("soundfile")
|
||||
safe_name = Path(filename).name.strip() or "audio"
|
||||
output = Path(folder_paths.output_directory)
|
||||
output.mkdir(parents=True, exist_ok=True)
|
||||
base = output / safe_name
|
||||
path = base.with_suffix(f".{extension}")
|
||||
counter = 2
|
||||
while path.exists():
|
||||
path = output / f"{safe_name}_{counter:05d}.{extension}"
|
||||
counter += 1
|
||||
soundfile.write(path, np.asarray(waveforms), int(sample_rate))
|
||||
return ()
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"AudioLDM2Node": AudioLDM2Node,
|
||||
"SaveAudioNode": SaveAudioNode,
|
||||
}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"AudioLDM2Node": "AudioLDM2",
|
||||
"SaveAudioNode": "Save Audio",
|
||||
}
|
||||
@@ -0,0 +1,35 @@
|
||||
"""A zero-download runtime report for portable support requests."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
|
||||
from .runtime import runtime_diagnostics
|
||||
|
||||
|
||||
class VLMRuntimeDiagnostics:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {"required": {}}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
RETURN_NAMES = ("runtime_report",)
|
||||
FUNCTION = "report"
|
||||
CATEGORY = "VLM Nodes/Diagnostics"
|
||||
OUTPUT_NODE = True
|
||||
|
||||
def report(self):
|
||||
return (
|
||||
json.dumps(
|
||||
runtime_diagnostics(),
|
||||
ensure_ascii=False,
|
||||
indent=2,
|
||||
sort_keys=True,
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"VLMRuntimeDiagnostics": VLMRuntimeDiagnostics}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"VLMRuntimeDiagnostics": "VLM Runtime Diagnostics"
|
||||
}
|
||||
@@ -0,0 +1,510 @@
|
||||
"""Florence-2 multitask caption, OCR, detection and segmentation node."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import hashlib
|
||||
import json
|
||||
import math
|
||||
from dataclasses import dataclass
|
||||
from numbers import Real
|
||||
|
||||
import torch
|
||||
from PIL import Image, ImageDraw
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
inference_context,
|
||||
model_device,
|
||||
move_inputs,
|
||||
pil_mask_to_tensor,
|
||||
pil_to_tensor,
|
||||
require_module,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
MODELS = {
|
||||
"Florence-2 base FT (fast)": "florence-community/Florence-2-base-ft",
|
||||
"Florence-2 large FT (recommended)": ("florence-community/Florence-2-large-ft"),
|
||||
}
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class FlorenceTaskSpec:
|
||||
"""Declarative contract for one official Florence-2 task."""
|
||||
|
||||
token: str
|
||||
input_kind: str
|
||||
output_kind: str
|
||||
|
||||
|
||||
TASKS = {
|
||||
"Caption": FlorenceTaskSpec("<CAPTION>", "none", "text"),
|
||||
"Detailed caption": FlorenceTaskSpec("<DETAILED_CAPTION>", "none", "text"),
|
||||
"More detailed caption": FlorenceTaskSpec(
|
||||
"<MORE_DETAILED_CAPTION>", "none", "text"
|
||||
),
|
||||
"OCR": FlorenceTaskSpec("<OCR>", "none", "text"),
|
||||
"OCR with regions": FlorenceTaskSpec("<OCR_WITH_REGION>", "none", "quad_boxes"),
|
||||
"Object detection": FlorenceTaskSpec("<OD>", "none", "boxes"),
|
||||
"Dense region caption": FlorenceTaskSpec("<DENSE_REGION_CAPTION>", "none", "boxes"),
|
||||
"Caption to phrase grounding": FlorenceTaskSpec(
|
||||
"<CAPTION_TO_PHRASE_GROUNDING>", "text", "boxes"
|
||||
),
|
||||
"Referring expression segmentation": FlorenceTaskSpec(
|
||||
"<REFERRING_EXPRESSION_SEGMENTATION>", "text", "polygons"
|
||||
),
|
||||
"Region to segmentation": FlorenceTaskSpec(
|
||||
"<REGION_TO_SEGMENTATION>", "region", "polygons"
|
||||
),
|
||||
"Open vocabulary detection": FlorenceTaskSpec(
|
||||
"<OPEN_VOCABULARY_DETECTION>", "text", "mixed"
|
||||
),
|
||||
"Region to category": FlorenceTaskSpec("<REGION_TO_CATEGORY>", "region", "text"),
|
||||
"Region to description": FlorenceTaskSpec(
|
||||
"<REGION_TO_DESCRIPTION>", "region", "text"
|
||||
),
|
||||
"Region to OCR": FlorenceTaskSpec("<REGION_TO_OCR>", "region", "text"),
|
||||
"Region proposals": FlorenceTaskSpec("<REGION_PROPOSAL>", "none", "boxes"),
|
||||
}
|
||||
|
||||
|
||||
def _clean_decoded_text(value):
|
||||
"""Remove generation wrappers without discarding Florence location tokens."""
|
||||
|
||||
text = str(value)
|
||||
for token in ("<s>", "</s>", "<pad>"):
|
||||
text = text.replace(token, "")
|
||||
return text.strip()
|
||||
|
||||
|
||||
def _select_region(region, image_index, batch_size):
|
||||
"""Select one core BOUNDING_BOX for the current image.
|
||||
|
||||
Core primitive boxes are dictionaries. Detection nodes may emit either a
|
||||
flat per-image list or a nested batch list, so both common shapes are
|
||||
accepted while ambiguous multi-region inputs fail explicitly.
|
||||
"""
|
||||
|
||||
if region is None or isinstance(region, dict):
|
||||
return region
|
||||
if not isinstance(region, (list, tuple)):
|
||||
raise TypeError("region must be a core BOUNDING_BOX dictionary.")
|
||||
if not region:
|
||||
return None
|
||||
|
||||
if all(isinstance(item, dict) for item in region):
|
||||
if len(region) == 1:
|
||||
return region[0]
|
||||
if len(region) == batch_size:
|
||||
return region[image_index]
|
||||
raise ValueError("Region tasks require exactly one BOUNDING_BOX per image.")
|
||||
|
||||
if len(region) != batch_size:
|
||||
raise ValueError("Batched BOUNDING_BOX input must contain one entry per image.")
|
||||
frame_regions = region[image_index]
|
||||
if isinstance(frame_regions, dict):
|
||||
return frame_regions
|
||||
if not isinstance(frame_regions, (list, tuple)) or len(frame_regions) != 1:
|
||||
raise ValueError(
|
||||
"Region tasks require exactly one BOUNDING_BOX per image; "
|
||||
"select a detection before connecting it."
|
||||
)
|
||||
if not isinstance(frame_regions[0], dict):
|
||||
raise TypeError("Each BOUNDING_BOX entry must be a dictionary.")
|
||||
return frame_regions[0]
|
||||
|
||||
|
||||
def _encode_region(region, image_size):
|
||||
"""Encode an absolute-pixel core BOUNDING_BOX as Florence location tokens."""
|
||||
|
||||
if not isinstance(region, dict):
|
||||
raise TypeError("region must be a core BOUNDING_BOX dictionary.")
|
||||
|
||||
try:
|
||||
x = float(region["x"])
|
||||
y = float(region["y"])
|
||||
box_width = float(region["width"])
|
||||
box_height = float(region["height"])
|
||||
except KeyError as exc:
|
||||
raise ValueError("region must contain x, y, width, and height.") from exc
|
||||
except (TypeError, ValueError) as exc:
|
||||
raise ValueError("region coordinates must be numeric.") from exc
|
||||
|
||||
values = (x, y, box_width, box_height)
|
||||
if not all(math.isfinite(value) for value in values):
|
||||
raise ValueError("region coordinates must be finite.")
|
||||
if box_width <= 0 or box_height <= 0:
|
||||
raise ValueError("region width and height must be greater than zero.")
|
||||
|
||||
image_width, image_height = image_size
|
||||
if image_width <= 0 or image_height <= 0:
|
||||
raise ValueError("image dimensions must be greater than zero.")
|
||||
|
||||
x0 = max(0.0, min(float(image_width), x))
|
||||
y0 = max(0.0, min(float(image_height), y))
|
||||
x1 = max(0.0, min(float(image_width), x + box_width))
|
||||
y1 = max(0.0, min(float(image_height), y + box_height))
|
||||
if x1 <= x0 or y1 <= y0:
|
||||
raise ValueError("region does not overlap the input image.")
|
||||
|
||||
coordinates = (
|
||||
x0 / image_width,
|
||||
y0 / image_height,
|
||||
x1 / image_width,
|
||||
y1 / image_height,
|
||||
)
|
||||
bins = [
|
||||
max(0, min(999, math.floor(coordinate * 1000))) for coordinate in coordinates
|
||||
]
|
||||
return "".join(f"<loc_{value}>" for value in bins)
|
||||
|
||||
|
||||
def _task_extra_input(task_name, text_input, region, image_size):
|
||||
"""Validate and prepare the optional suffix for a Florence task prompt."""
|
||||
|
||||
try:
|
||||
spec = TASKS[task_name]
|
||||
except KeyError as exc:
|
||||
raise ValueError(f"Unsupported Florence-2 task: {task_name}") from exc
|
||||
|
||||
text = (text_input or "").strip()
|
||||
if spec.input_kind == "none":
|
||||
if text:
|
||||
raise ValueError(f"{task_name} does not accept text input.")
|
||||
if region is not None:
|
||||
raise ValueError(f"{task_name} does not accept a region input.")
|
||||
return ""
|
||||
if spec.input_kind == "text":
|
||||
if not text:
|
||||
raise ValueError(f"{task_name} requires text input.")
|
||||
if region is not None:
|
||||
raise ValueError(f"{task_name} does not accept a region input.")
|
||||
return text
|
||||
if spec.input_kind == "region":
|
||||
if text:
|
||||
raise ValueError(
|
||||
f"{task_name} uses the region input and does not accept text."
|
||||
)
|
||||
if region is None:
|
||||
raise ValueError(f"{task_name} requires a connected BOUNDING_BOX region.")
|
||||
return _encode_region(region, image_size)
|
||||
raise RuntimeError(f"Unknown Florence task input kind: {spec.input_kind}")
|
||||
|
||||
|
||||
class FlorencePredictor:
|
||||
def __init__(self, model_label):
|
||||
transformers = require_module("transformers")
|
||||
repo_id = MODELS[model_label]
|
||||
path = snapshot_download(
|
||||
repo_id,
|
||||
f"florence2/{repo_id.replace('/', '--')}",
|
||||
ignore_patterns=["*.bin"],
|
||||
)
|
||||
self.dtype = torch_dtype("float16")
|
||||
self.processor = transformers.Florence2Processor.from_pretrained(path)
|
||||
model = transformers.Florence2ForConditionalGeneration.from_pretrained(
|
||||
path,
|
||||
dtype=self.dtype,
|
||||
)
|
||||
model.eval()
|
||||
self.handle = ManagedTorchModel(model, processor=self.processor)
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
def run(self, image, task_token, text, max_new_tokens, beams):
|
||||
prompt = task_token + (text.strip() if text.strip() else "")
|
||||
inputs = self.processor(text=prompt, images=image, return_tensors="pt")
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
inputs = move_inputs(inputs, device, floating_dtype=self.dtype)
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
generated = model.generate(
|
||||
**inputs,
|
||||
max_new_tokens=int(max_new_tokens),
|
||||
num_beams=int(beams),
|
||||
do_sample=False,
|
||||
early_stopping=int(beams) > 1,
|
||||
)
|
||||
raw = self.processor.batch_decode(generated, skip_special_tokens=False)[0]
|
||||
parsed = self.processor.post_process_generation(
|
||||
raw, task=task_token, image_size=image.size
|
||||
)
|
||||
return raw, parsed
|
||||
|
||||
|
||||
def _json_default(value):
|
||||
if hasattr(value, "tolist"):
|
||||
return value.tolist()
|
||||
return str(value)
|
||||
|
||||
|
||||
_SPATIAL_KEYS = frozenset(
|
||||
{
|
||||
"bboxes",
|
||||
"quad_boxes",
|
||||
"polygons",
|
||||
"labels",
|
||||
"bboxes_labels",
|
||||
"polygons_labels",
|
||||
}
|
||||
)
|
||||
|
||||
|
||||
def _spatial_result(parsed):
|
||||
if not isinstance(parsed, dict):
|
||||
return {}
|
||||
if _SPATIAL_KEYS.intersection(parsed):
|
||||
return parsed
|
||||
result = next(iter(parsed.values()), {})
|
||||
return result if isinstance(result, dict) else {}
|
||||
|
||||
|
||||
def _stable_color(kind, index, label):
|
||||
key = f"{kind}:{index}:{label}".encode("utf-8", errors="replace")
|
||||
digest = hashlib.blake2b(key, digest_size=3).digest()
|
||||
return tuple(64 + channel % 192 for channel in digest)
|
||||
|
||||
|
||||
def _points(values, image_size):
|
||||
if not isinstance(values, (list, tuple)) or len(values) < 6:
|
||||
return []
|
||||
width, height = image_size
|
||||
points = []
|
||||
for index in range(0, len(values) - 1, 2):
|
||||
x, y = values[index], values[index + 1]
|
||||
if not isinstance(x, Real) or not isinstance(y, Real):
|
||||
return []
|
||||
if not math.isfinite(float(x)) or not math.isfinite(float(y)):
|
||||
return []
|
||||
points.append(
|
||||
(
|
||||
max(0, min(width - 1, round(float(x)))),
|
||||
max(0, min(height - 1, round(float(y)))),
|
||||
)
|
||||
)
|
||||
return points
|
||||
|
||||
|
||||
def _box(values, image_size):
|
||||
if not isinstance(values, (list, tuple)) or len(values) < 4:
|
||||
return None
|
||||
if not all(isinstance(value, Real) for value in values[:4]):
|
||||
return None
|
||||
coordinates = [float(value) for value in values[:4]]
|
||||
if not all(math.isfinite(value) for value in coordinates):
|
||||
return None
|
||||
x0, y0, x1, y1 = coordinates
|
||||
x0, x1 = sorted((x0, x1))
|
||||
y0, y1 = sorted((y0, y1))
|
||||
width, height = image_size
|
||||
x0 = max(0, min(width - 1, round(x0)))
|
||||
x1 = max(0, min(width - 1, round(x1)))
|
||||
y0 = max(0, min(height - 1, round(y0)))
|
||||
y1 = max(0, min(height - 1, round(y1)))
|
||||
if x1 <= x0 or y1 <= y0:
|
||||
return None
|
||||
return x0, y0, x1, y1
|
||||
|
||||
|
||||
def _polygon_list(group):
|
||||
if not isinstance(group, (list, tuple)) or not group:
|
||||
return []
|
||||
if isinstance(group[0], Real):
|
||||
return [group]
|
||||
return [item for item in group if isinstance(item, (list, tuple))]
|
||||
|
||||
|
||||
def _label_with_score(labels, scores, index):
|
||||
label = str(labels[index]) if index < len(labels) else ""
|
||||
if index < len(scores) and isinstance(scores[index], Real):
|
||||
score = f"{float(scores[index]):.3f}"
|
||||
return f"{label} {score}".strip()
|
||||
return label
|
||||
|
||||
|
||||
def _draw_label(draw, position, text, color, image_size):
|
||||
if not text:
|
||||
return
|
||||
x, y = position
|
||||
try:
|
||||
left, top, right, bottom = draw.textbbox((0, 0), text)
|
||||
text_width, text_height = right - left, bottom - top
|
||||
except AttributeError:
|
||||
text_width, text_height = draw.textlength(text), 11
|
||||
width, height = image_size
|
||||
x = max(0, min(width - text_width - 4, x))
|
||||
y = max(0, min(height - text_height - 4, y))
|
||||
background = (0, 0, 0) if sum(color) > 360 else (255, 255, 255)
|
||||
foreground = (255, 255, 255) if background == (0, 0, 0) else (0, 0, 0)
|
||||
draw.rectangle(
|
||||
(x, y, x + text_width + 4, y + text_height + 4),
|
||||
fill=background,
|
||||
)
|
||||
draw.text((x + 2, y + 2), text, fill=foreground)
|
||||
|
||||
|
||||
def _visualize(image, parsed):
|
||||
result = _spatial_result(parsed)
|
||||
mask = Image.new("L", image.size, 0)
|
||||
visual = image.copy().convert("RGB")
|
||||
mask_draw = ImageDraw.Draw(mask)
|
||||
draw = ImageDraw.Draw(visual)
|
||||
width = max(2, min(8, round(min(image.size) / 256 * 3)))
|
||||
labels = result.get("labels", [])
|
||||
scores = result.get("scores", [])
|
||||
|
||||
box_labels = result.get("bboxes_labels", labels)
|
||||
for index, values in enumerate(result.get("bboxes", [])):
|
||||
box = _box(values, image.size)
|
||||
if box is None:
|
||||
continue
|
||||
label = _label_with_score(box_labels, scores, index)
|
||||
color = _stable_color("box", index, label)
|
||||
mask_draw.rectangle(box, fill=255)
|
||||
draw.rectangle(box, outline=color, width=width)
|
||||
_draw_label(draw, (box[0], box[1]), label, color, image.size)
|
||||
|
||||
for index, values in enumerate(result.get("quad_boxes", [])):
|
||||
points = _points(values, image.size)
|
||||
if len(points) < 3:
|
||||
continue
|
||||
label = _label_with_score(labels, scores, index)
|
||||
color = _stable_color("quad", index, label)
|
||||
mask_draw.polygon(points, fill=255)
|
||||
draw.line(points + [points[0]], fill=color, width=width)
|
||||
_draw_label(draw, points[0], label, color, image.size)
|
||||
|
||||
polygon_labels = result.get("polygons_labels", labels)
|
||||
for index, group in enumerate(result.get("polygons", [])):
|
||||
label = _label_with_score(polygon_labels, scores, index)
|
||||
color = _stable_color("polygon", index, label)
|
||||
label_drawn = False
|
||||
for polygon in _polygon_list(group):
|
||||
points = _points(polygon, image.size)
|
||||
if len(points) < 3:
|
||||
continue
|
||||
mask_draw.polygon(points, fill=255)
|
||||
draw.line(points + [points[0]], fill=color, width=width)
|
||||
if not label_drawn:
|
||||
_draw_label(draw, points[0], label, color, image.size)
|
||||
label_drawn = True
|
||||
return mask, visual
|
||||
|
||||
|
||||
class Florence2(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"task": (list(TASKS),),
|
||||
"text_input": (
|
||||
"STRING",
|
||||
{
|
||||
"default": "",
|
||||
"multiline": True,
|
||||
"tooltip": (
|
||||
"Required only for phrase grounding, referring-expression "
|
||||
"segmentation, and open-vocabulary detection."
|
||||
),
|
||||
},
|
||||
),
|
||||
"model": (
|
||||
list(MODELS),
|
||||
{"default": "Florence-2 large FT (recommended)"},
|
||||
),
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 1024, "min": 1, "max": 4096},
|
||||
),
|
||||
"beams": ("INT", {"default": 3, "min": 1, "max": 8}),
|
||||
},
|
||||
"optional": {
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
"region": (
|
||||
"BOUNDING_BOX",
|
||||
{
|
||||
"tooltip": (
|
||||
"Core bounding box input required by Region to "
|
||||
"Segmentation/Category/Description/OCR."
|
||||
)
|
||||
},
|
||||
),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING", "STRING", "MASK", "IMAGE")
|
||||
RETURN_NAMES = ("text", "structured_json", "mask", "visualization")
|
||||
FUNCTION = "run"
|
||||
CATEGORY = "VLM Nodes/Florence-2"
|
||||
|
||||
def run(
|
||||
self,
|
||||
image,
|
||||
task,
|
||||
text_input,
|
||||
model,
|
||||
max_new_tokens,
|
||||
beams,
|
||||
unload_after=False,
|
||||
region=None,
|
||||
):
|
||||
images = tensor_batch_to_pil(image)
|
||||
if not images:
|
||||
raise ValueError("Florence-2 requires at least one input image.")
|
||||
try:
|
||||
spec = TASKS[task]
|
||||
except KeyError as exc:
|
||||
raise ValueError(f"Unsupported Florence-2 task: {task}") from exc
|
||||
|
||||
extra_inputs = []
|
||||
for index, pil_image in enumerate(images):
|
||||
selected_region = _select_region(region, index, len(images))
|
||||
extra_inputs.append(
|
||||
_task_extra_input(
|
||||
task,
|
||||
text_input,
|
||||
selected_region,
|
||||
pil_image.size,
|
||||
)
|
||||
)
|
||||
|
||||
predictor = self.get_or_create_model(model, lambda: FlorencePredictor(model))
|
||||
texts, records, masks, visuals = [], [], [], []
|
||||
try:
|
||||
for pil_image, extra_input in zip(images, extra_inputs):
|
||||
raw, parsed = predictor.run(
|
||||
pil_image,
|
||||
spec.token,
|
||||
extra_input,
|
||||
max_new_tokens,
|
||||
beams,
|
||||
)
|
||||
texts.append(_clean_decoded_text(raw))
|
||||
records.append(parsed)
|
||||
mask, visual = _visualize(pil_image, parsed)
|
||||
masks.append(pil_mask_to_tensor(mask))
|
||||
visuals.append(pil_to_tensor(visual))
|
||||
return (
|
||||
batch_text(texts),
|
||||
json.dumps(
|
||||
records,
|
||||
ensure_ascii=False,
|
||||
default=_json_default,
|
||||
sort_keys=True,
|
||||
),
|
||||
torch.cat(masks),
|
||||
torch.cat(visuals),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"Florence2": Florence2}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Florence2": "Florence-2 Multitask Vision"}
|
||||
@@ -0,0 +1,413 @@
|
||||
"""Dependency-light geometry, mask, color, and association primitives."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import colorsys
|
||||
import hashlib
|
||||
import math
|
||||
from dataclasses import dataclass
|
||||
from typing import Iterable, Mapping
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import Image, ImageDraw
|
||||
|
||||
from .vision_types import BoxXYXY, Detection, PointXY, Polygon
|
||||
|
||||
|
||||
def _dimensions(width: int, height: int) -> tuple[int, int]:
|
||||
if not isinstance(width, int) or width <= 0:
|
||||
raise ValueError("width must be a positive integer.")
|
||||
if not isinstance(height, int) or height <= 0:
|
||||
raise ValueError("height must be a positive integer.")
|
||||
return width, height
|
||||
|
||||
|
||||
def _ordered_box(box: Iterable[float]) -> BoxXYXY:
|
||||
values = tuple(float(value) for value in box)
|
||||
if len(values) != 4 or not all(math.isfinite(value) for value in values):
|
||||
raise ValueError("A box must contain four finite xyxy values.")
|
||||
x1, y1, x2, y2 = values
|
||||
if x2 < x1 or y2 < y1:
|
||||
raise ValueError("A box must satisfy x2 >= x1 and y2 >= y1.")
|
||||
return x1, y1, x2, y2
|
||||
|
||||
|
||||
def clip_box(box: Iterable[float], width: int, height: int) -> BoxXYXY:
|
||||
"""Clamp a pixel xyxy box to an image, preserving exclusive x2/y2."""
|
||||
|
||||
width, height = _dimensions(width, height)
|
||||
x1, y1, x2, y2 = _ordered_box(box)
|
||||
return (
|
||||
min(max(x1, 0.0), float(width)),
|
||||
min(max(y1, 0.0), float(height)),
|
||||
min(max(x2, 0.0), float(width)),
|
||||
min(max(y2, 0.0), float(height)),
|
||||
)
|
||||
|
||||
|
||||
def clip_polygon(
|
||||
polygon: Iterable[Iterable[float]],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> Polygon:
|
||||
width, height = _dimensions(width, height)
|
||||
points = []
|
||||
for point in polygon:
|
||||
values = tuple(float(value) for value in point)
|
||||
if len(values) != 2 or not all(math.isfinite(value) for value in values):
|
||||
raise ValueError("Polygon points must contain two finite values.")
|
||||
points.append(
|
||||
(
|
||||
min(max(values[0], 0.0), float(width)),
|
||||
min(max(values[1], 0.0), float(height)),
|
||||
)
|
||||
)
|
||||
if len(points) < 3:
|
||||
raise ValueError("A polygon requires at least three points.")
|
||||
return tuple(points)
|
||||
|
||||
|
||||
def normalize_box(
|
||||
box: Iterable[float],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> BoxXYXY:
|
||||
width, height = _dimensions(width, height)
|
||||
x1, y1, x2, y2 = clip_box(box, width, height)
|
||||
return x1 / width, y1 / height, x2 / width, y2 / height
|
||||
|
||||
|
||||
def denormalize_box(
|
||||
box: Iterable[float],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> BoxXYXY:
|
||||
width, height = _dimensions(width, height)
|
||||
x1, y1, x2, y2 = _ordered_box(box)
|
||||
if any(value < 0.0 or value > 1.0 for value in (x1, y1, x2, y2)):
|
||||
raise ValueError("Normalized box coordinates must be between 0 and 1.")
|
||||
return x1 * width, y1 * height, x2 * width, y2 * height
|
||||
|
||||
|
||||
def box_area(box: Iterable[float]) -> float:
|
||||
x1, y1, x2, y2 = _ordered_box(box)
|
||||
return (x2 - x1) * (y2 - y1)
|
||||
|
||||
|
||||
def box_center(box: Iterable[float]) -> PointXY:
|
||||
x1, y1, x2, y2 = _ordered_box(box)
|
||||
return (x1 + x2) * 0.5, (y1 + y2) * 0.5
|
||||
|
||||
|
||||
def polygon_area(polygon: Iterable[Iterable[float]]) -> float:
|
||||
points = [tuple(float(value) for value in point) for point in polygon]
|
||||
if len(points) < 3 or any(len(point) != 2 for point in points):
|
||||
raise ValueError("A polygon requires at least three xy points.")
|
||||
if any(not math.isfinite(value) for point in points for value in point):
|
||||
raise ValueError("Polygon coordinates must be finite.")
|
||||
twice_area = sum(
|
||||
x1 * y2 - x2 * y1 for (x1, y1), (x2, y2) in zip(points, points[1:] + points[:1])
|
||||
)
|
||||
return abs(twice_area) * 0.5
|
||||
|
||||
|
||||
def bbox_iou(first: Iterable[float], second: Iterable[float]) -> float:
|
||||
ax1, ay1, ax2, ay2 = _ordered_box(first)
|
||||
bx1, by1, bx2, by2 = _ordered_box(second)
|
||||
intersection = max(0.0, min(ax2, bx2) - max(ax1, bx1)) * max(
|
||||
0.0, min(ay2, by2) - max(ay1, by1)
|
||||
)
|
||||
union = box_area(first) + box_area(second) - intersection
|
||||
return intersection / union if union > 0 else 0.0
|
||||
|
||||
|
||||
def mask_iou(
|
||||
first: torch.Tensor | np.ndarray,
|
||||
second: torch.Tensor | np.ndarray,
|
||||
*,
|
||||
threshold: float = 0.5,
|
||||
) -> float:
|
||||
first_tensor = torch.as_tensor(first)
|
||||
second_tensor = torch.as_tensor(second)
|
||||
if first_tensor.ndim != 2 or second_tensor.ndim != 2:
|
||||
raise ValueError("Masks must have shape [height, width].")
|
||||
if first_tensor.shape != second_tensor.shape:
|
||||
raise ValueError("Masks must have the same shape.")
|
||||
first_bool = first_tensor > float(threshold)
|
||||
second_bool = second_tensor > float(threshold)
|
||||
intersection = torch.logical_and(first_bool, second_bool).sum().item()
|
||||
union = torch.logical_or(first_bool, second_bool).sum().item()
|
||||
return float(intersection / union) if union else 0.0
|
||||
|
||||
|
||||
def deterministic_color(value: object) -> tuple[int, int, int]:
|
||||
"""Return a readable RGB color that is stable across Python processes."""
|
||||
|
||||
digest = hashlib.sha256(str(value).encode("utf-8")).digest()
|
||||
hue = int.from_bytes(digest[:2], "big") / 65535.0
|
||||
saturation = 0.62 + digest[2] / 255.0 * 0.22
|
||||
brightness = 0.78 + digest[3] / 255.0 * 0.17
|
||||
return tuple(
|
||||
round(channel * 255)
|
||||
for channel in colorsys.hsv_to_rgb(hue, saturation, brightness)
|
||||
)
|
||||
|
||||
|
||||
def box_to_mask(
|
||||
box: Iterable[float],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> torch.Tensor:
|
||||
width, height = _dimensions(width, height)
|
||||
x1, y1, x2, y2 = clip_box(box, width, height)
|
||||
left = max(0, min(width, math.floor(x1)))
|
||||
top = max(0, min(height, math.floor(y1)))
|
||||
right = max(left, min(width, math.ceil(x2)))
|
||||
bottom = max(top, min(height, math.ceil(y2)))
|
||||
mask = torch.zeros((height, width), dtype=torch.float32)
|
||||
mask[top:bottom, left:right] = 1.0
|
||||
return mask
|
||||
|
||||
|
||||
def polygon_to_mask(
|
||||
polygon: Iterable[Iterable[float]],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> torch.Tensor:
|
||||
width, height = _dimensions(width, height)
|
||||
points = clip_polygon(polygon, width, height)
|
||||
canvas = Image.new("L", (width, height), 0)
|
||||
ImageDraw.Draw(canvas).polygon(points, fill=255)
|
||||
array = np.asarray(canvas, dtype=np.float32) / 255.0
|
||||
return torch.from_numpy(array.copy())
|
||||
|
||||
|
||||
def quad_to_mask(
|
||||
quad: Iterable[Iterable[float]],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> torch.Tensor:
|
||||
points = tuple(tuple(point) for point in quad)
|
||||
if len(points) != 4:
|
||||
raise ValueError("A quad must contain exactly four points.")
|
||||
return polygon_to_mask(points, width, height)
|
||||
|
||||
|
||||
def detection_to_mask(
|
||||
detection: Detection,
|
||||
width: int,
|
||||
height: int,
|
||||
) -> torch.Tensor:
|
||||
"""Rasterize the most precise geometry available on a detection."""
|
||||
|
||||
width, height = _dimensions(width, height)
|
||||
if not isinstance(detection, Detection):
|
||||
raise TypeError("detection must be a Detection.")
|
||||
if detection.mask is not None:
|
||||
if tuple(detection.mask.shape) != (height, width):
|
||||
raise ValueError("Detection mask shape does not match the image.")
|
||||
return detection.mask.detach().to(dtype=torch.float32).clamp(0, 1).clone()
|
||||
if detection.polygon is not None:
|
||||
return polygon_to_mask(detection.polygon, width, height)
|
||||
if detection.quad is not None:
|
||||
return quad_to_mask(detection.quad, width, height)
|
||||
return box_to_mask(detection.bbox_xyxy, width, height)
|
||||
|
||||
|
||||
def individual_detection_masks(
|
||||
detections: Iterable[Detection],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> torch.Tensor:
|
||||
width, height = _dimensions(width, height)
|
||||
masks = [detection_to_mask(detection, width, height) for detection in detections]
|
||||
if not masks:
|
||||
return torch.zeros((0, height, width), dtype=torch.float32)
|
||||
return torch.stack(masks).to(dtype=torch.float32)
|
||||
|
||||
|
||||
def union_detection_mask(
|
||||
detections: Iterable[Detection],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> torch.Tensor:
|
||||
masks = individual_detection_masks(detections, width, height)
|
||||
if masks.shape[0] == 0:
|
||||
return torch.zeros((height, width), dtype=torch.float32)
|
||||
return masks.amax(dim=0).clamp(0, 1)
|
||||
|
||||
|
||||
def bbox_from_mask(
|
||||
mask: torch.Tensor | np.ndarray,
|
||||
*,
|
||||
threshold: float = 0.5,
|
||||
) -> BoxXYXY | None:
|
||||
value = torch.as_tensor(mask)
|
||||
if value.ndim != 2:
|
||||
raise ValueError("mask must have shape [height, width].")
|
||||
locations = torch.nonzero(value > float(threshold), as_tuple=False)
|
||||
if locations.numel() == 0:
|
||||
return None
|
||||
y1, x1 = locations.amin(dim=0).tolist()
|
||||
y2, x2 = locations.amax(dim=0).tolist()
|
||||
return float(x1), float(y1), float(x2 + 1), float(y2 + 1)
|
||||
|
||||
|
||||
def translate_box(
|
||||
box: Iterable[float],
|
||||
dx: float,
|
||||
dy: float,
|
||||
) -> BoxXYXY:
|
||||
x1, y1, x2, y2 = _ordered_box(box)
|
||||
dx = float(dx)
|
||||
dy = float(dy)
|
||||
if not math.isfinite(dx) or not math.isfinite(dy):
|
||||
raise ValueError("Box motion must be finite.")
|
||||
return x1 + dx, y1 + dy, x2 + dx, y2 + dy
|
||||
|
||||
|
||||
def expand_box(
|
||||
box: Iterable[float],
|
||||
width: int,
|
||||
height: int,
|
||||
*,
|
||||
padding: float = 0.0,
|
||||
square: bool = False,
|
||||
) -> BoxXYXY:
|
||||
"""Pad and optionally square a box around its center, then clip it."""
|
||||
|
||||
width, height = _dimensions(width, height)
|
||||
if not math.isfinite(float(padding)) or padding < 0:
|
||||
raise ValueError("padding must be finite and non-negative.")
|
||||
x1, y1, x2, y2 = _ordered_box(box)
|
||||
x1 -= padding
|
||||
y1 -= padding
|
||||
x2 += padding
|
||||
y2 += padding
|
||||
if square:
|
||||
center_x, center_y = (x1 + x2) * 0.5, (y1 + y2) * 0.5
|
||||
half = max(x2 - x1, y2 - y1) * 0.5
|
||||
x1, y1, x2, y2 = (
|
||||
center_x - half,
|
||||
center_y - half,
|
||||
center_x + half,
|
||||
center_y + half,
|
||||
)
|
||||
side = x2 - x1
|
||||
if side <= width:
|
||||
if x1 < 0:
|
||||
x2 -= x1
|
||||
x1 = 0.0
|
||||
elif x2 > width:
|
||||
x1 -= x2 - width
|
||||
x2 = float(width)
|
||||
if side <= height:
|
||||
if y1 < 0:
|
||||
y2 -= y1
|
||||
y1 = 0.0
|
||||
elif y2 > height:
|
||||
y1 -= y2 - height
|
||||
y2 = float(height)
|
||||
return clip_box((x1, y1, x2, y2), width, height)
|
||||
|
||||
|
||||
@dataclass(frozen=True, slots=True)
|
||||
class AssociationResult:
|
||||
"""Stable one-to-one detection assignment by descending overlap."""
|
||||
|
||||
matches: tuple[tuple[int, int, float], ...]
|
||||
unmatched_previous: tuple[int, ...]
|
||||
unmatched_current: tuple[int, ...]
|
||||
|
||||
|
||||
def associate_detections(
|
||||
previous: Iterable[Detection],
|
||||
current: Iterable[Detection],
|
||||
*,
|
||||
minimum_iou: float = 0.3,
|
||||
label_aware: bool = True,
|
||||
motion_by_track: Mapping[int, tuple[float, float]] | None = None,
|
||||
) -> AssociationResult:
|
||||
"""Associate detections without SciPy or backend-specific operators.
|
||||
|
||||
Candidates are greedily selected by descending IoU with deterministic
|
||||
index tie-breaks. Optional per-track motion offsets predict the previous
|
||||
box before overlap is measured.
|
||||
"""
|
||||
|
||||
previous_items = tuple(previous)
|
||||
current_items = tuple(current)
|
||||
if not 0.0 <= float(minimum_iou) <= 1.0:
|
||||
raise ValueError("minimum_iou must be between 0 and 1.")
|
||||
if any(not isinstance(item, Detection) for item in previous_items):
|
||||
raise TypeError("previous must contain Detection values.")
|
||||
if any(not isinstance(item, Detection) for item in current_items):
|
||||
raise TypeError("current must contain Detection values.")
|
||||
|
||||
candidates = []
|
||||
for previous_index, old in enumerate(previous_items):
|
||||
old_box = old.bbox_xyxy
|
||||
if old.track_id is not None and motion_by_track:
|
||||
motion = motion_by_track.get(old.track_id)
|
||||
if motion is not None:
|
||||
old_box = translate_box(old_box, motion[0], motion[1])
|
||||
for current_index, new in enumerate(current_items):
|
||||
if (
|
||||
label_aware
|
||||
and old.label is not None
|
||||
and new.label is not None
|
||||
and " ".join(old.label.casefold().split())
|
||||
!= " ".join(new.label.casefold().split())
|
||||
):
|
||||
continue
|
||||
overlap = bbox_iou(old_box, new.bbox_xyxy)
|
||||
if overlap >= float(minimum_iou):
|
||||
candidates.append((-overlap, previous_index, current_index, overlap))
|
||||
|
||||
matched_previous: set[int] = set()
|
||||
matched_current: set[int] = set()
|
||||
matches = []
|
||||
for _negative, previous_index, current_index, overlap in sorted(candidates):
|
||||
if previous_index in matched_previous or current_index in matched_current:
|
||||
continue
|
||||
matched_previous.add(previous_index)
|
||||
matched_current.add(current_index)
|
||||
matches.append((previous_index, current_index, overlap))
|
||||
|
||||
return AssociationResult(
|
||||
matches=tuple(matches),
|
||||
unmatched_previous=tuple(
|
||||
index
|
||||
for index in range(len(previous_items))
|
||||
if index not in matched_previous
|
||||
),
|
||||
unmatched_current=tuple(
|
||||
index for index in range(len(current_items)) if index not in matched_current
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
__all__ = [
|
||||
"AssociationResult",
|
||||
"associate_detections",
|
||||
"bbox_from_mask",
|
||||
"bbox_iou",
|
||||
"box_area",
|
||||
"box_center",
|
||||
"box_to_mask",
|
||||
"clip_box",
|
||||
"clip_polygon",
|
||||
"denormalize_box",
|
||||
"detection_to_mask",
|
||||
"deterministic_color",
|
||||
"expand_box",
|
||||
"individual_detection_masks",
|
||||
"mask_iou",
|
||||
"normalize_box",
|
||||
"polygon_area",
|
||||
"polygon_to_mask",
|
||||
"quad_to_mask",
|
||||
"translate_box",
|
||||
"union_detection_mask",
|
||||
]
|
||||
@@ -0,0 +1,532 @@
|
||||
"""Fast open-vocabulary object detection with maintained Transformers models.
|
||||
|
||||
The node deliberately presents one stable ComfyUI interface while keeping
|
||||
model-specific preprocessing and postprocessing behind a small adapter. Model
|
||||
downloads are lazy, inference participates in ComfyUI's VRAM management, and
|
||||
all spatial output uses the pack's versioned pixel-coordinate contract.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import math
|
||||
from dataclasses import dataclass
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import ImageDraw
|
||||
|
||||
from .geometry import deterministic_color
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
inference_context,
|
||||
model_device,
|
||||
move_inputs,
|
||||
require_module,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
from .vision_types import (
|
||||
VLM_DETECTIONS,
|
||||
Detection,
|
||||
DetectionSequence,
|
||||
FrameDetections,
|
||||
)
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class DetectorSpec:
|
||||
model_id: str
|
||||
cache_name: str
|
||||
family: str
|
||||
description: str
|
||||
|
||||
|
||||
MODEL_SPECS = {
|
||||
"Grounding DINO Tiny (fast)": DetectorSpec(
|
||||
"IDEA-Research/grounding-dino-tiny",
|
||||
"grounding-dino-tiny",
|
||||
"grounding_dino",
|
||||
"Fast, accurate open-vocabulary grounding.",
|
||||
),
|
||||
"Grounding DINO Base": DetectorSpec(
|
||||
"IDEA-Research/grounding-dino-base",
|
||||
"grounding-dino-base",
|
||||
"grounding_dino",
|
||||
"Higher-quality open-vocabulary grounding.",
|
||||
),
|
||||
"OWLv2 Base Ensemble": DetectorSpec(
|
||||
"google/owlv2-base-patch16-ensemble",
|
||||
"owlv2-base-patch16-ensemble",
|
||||
"owlv2",
|
||||
"Strong zero-shot detector for lists of visual concepts.",
|
||||
),
|
||||
"OmDet Turbo Swin Tiny (fast)": DetectorSpec(
|
||||
"omlab/omdet-turbo-swin-tiny-hf",
|
||||
"omdet-turbo-swin-tiny",
|
||||
"omdet",
|
||||
"Efficient real-time-oriented open-vocabulary detector.",
|
||||
),
|
||||
}
|
||||
|
||||
|
||||
def parse_labels(value: str) -> list[str]:
|
||||
"""Parse user concepts without splitting meaningful multi-word labels."""
|
||||
|
||||
labels: list[str] = []
|
||||
for line in str(value or "").replace(";", "\n").splitlines():
|
||||
for candidate in line.split(","):
|
||||
label = " ".join(candidate.strip().split())
|
||||
if label and label not in labels:
|
||||
labels.append(label)
|
||||
if not labels:
|
||||
raise ValueError("Enter at least one object label or referring phrase.")
|
||||
return labels
|
||||
|
||||
|
||||
def _safe_score(value: Any) -> float:
|
||||
score = float(value.item() if hasattr(value, "item") else value)
|
||||
return min(1.0, max(0.0, score))
|
||||
|
||||
|
||||
def _result_labels(result: dict[str, Any], labels: list[str]) -> list[str]:
|
||||
text_labels = result.get("text_labels")
|
||||
if text_labels is not None:
|
||||
return [str(label) for label in text_labels]
|
||||
|
||||
raw_labels = result.get("labels", result.get("classes", []))
|
||||
resolved = []
|
||||
for value in raw_labels:
|
||||
if isinstance(value, str):
|
||||
resolved.append(value)
|
||||
continue
|
||||
index = int(value.item() if hasattr(value, "item") else value)
|
||||
resolved.append(labels[index] if 0 <= index < len(labels) else str(index))
|
||||
return resolved
|
||||
|
||||
|
||||
def result_to_detections(
|
||||
result: dict[str, Any],
|
||||
*,
|
||||
labels: list[str],
|
||||
width: int,
|
||||
height: int,
|
||||
frame_index: int,
|
||||
timestamp: float,
|
||||
source: str,
|
||||
max_detections: int,
|
||||
) -> tuple[Detection, ...]:
|
||||
"""Normalize a Transformers detector result into immutable detections."""
|
||||
|
||||
boxes = result.get("boxes", ())
|
||||
scores = result.get("scores", ())
|
||||
resolved_labels = _result_labels(result, labels)
|
||||
count = min(len(boxes), len(scores), len(resolved_labels))
|
||||
records = []
|
||||
for index in range(count):
|
||||
box_value = boxes[index]
|
||||
if hasattr(box_value, "detach"):
|
||||
box_value = box_value.detach().to(device="cpu").tolist()
|
||||
x1, y1, x2, y2 = (float(value) for value in box_value)
|
||||
x1 = min(float(width), max(0.0, x1))
|
||||
y1 = min(float(height), max(0.0, y1))
|
||||
x2 = min(float(width), max(x1, x2))
|
||||
y2 = min(float(height), max(y1, y2))
|
||||
if x2 <= x1 or y2 <= y1:
|
||||
continue
|
||||
records.append(
|
||||
Detection(
|
||||
bbox_xyxy=(x1, y1, x2, y2),
|
||||
label=resolved_labels[index].strip() or None,
|
||||
score=_safe_score(scores[index]),
|
||||
frame_index=frame_index,
|
||||
timestamp=timestamp,
|
||||
source=source,
|
||||
metadata={"model_id": source},
|
||||
)
|
||||
)
|
||||
records.sort(
|
||||
key=lambda item: (
|
||||
-(item.score or 0.0),
|
||||
item.label or "",
|
||||
item.bbox_xyxy,
|
||||
)
|
||||
)
|
||||
return tuple(records[:max_detections])
|
||||
|
||||
|
||||
def _post_process(
|
||||
processor: Any,
|
||||
spec: DetectorSpec,
|
||||
outputs: Any,
|
||||
inputs: dict[str, Any],
|
||||
labels: list[str],
|
||||
sizes: list[tuple[int, int]],
|
||||
box_threshold: float,
|
||||
text_threshold: float,
|
||||
nms_threshold: float,
|
||||
max_detections: int,
|
||||
) -> list[dict[str, Any]]:
|
||||
if spec.family == "grounding_dino":
|
||||
kwargs = {
|
||||
"threshold": float(box_threshold),
|
||||
"text_threshold": float(text_threshold),
|
||||
"target_sizes": sizes,
|
||||
}
|
||||
input_ids = inputs.get("input_ids")
|
||||
if input_ids is not None:
|
||||
kwargs["input_ids"] = input_ids
|
||||
return processor.post_process_grounded_object_detection(outputs, **kwargs)
|
||||
if spec.family == "omdet":
|
||||
return processor.post_process_grounded_object_detection(
|
||||
outputs,
|
||||
text_labels=[labels] * len(sizes),
|
||||
threshold=float(box_threshold),
|
||||
nms_threshold=float(nms_threshold),
|
||||
target_sizes=sizes,
|
||||
max_num_det=int(max_detections),
|
||||
)
|
||||
return processor.post_process_grounded_object_detection(
|
||||
outputs,
|
||||
threshold=float(box_threshold),
|
||||
target_sizes=sizes,
|
||||
text_labels=[labels] * len(sizes),
|
||||
)
|
||||
|
||||
|
||||
class OpenVocabularyDetector:
|
||||
def __init__(self, spec: DetectorSpec, precision: str = "auto"):
|
||||
transformers = require_module("transformers")
|
||||
model_path = snapshot_download(
|
||||
spec.model_id,
|
||||
spec.cache_name,
|
||||
ignore_patterns=["*.bin", "*.gguf", "*.onnx", "*.tflite"],
|
||||
)
|
||||
processor = transformers.AutoProcessor.from_pretrained(model_path)
|
||||
model_class = transformers.AutoModelForZeroShotObjectDetection
|
||||
dtype = torch_dtype(precision)
|
||||
model = model_class.from_pretrained(model_path, dtype=dtype)
|
||||
model.eval()
|
||||
self.spec = spec
|
||||
self.dtype = dtype
|
||||
self.processor = processor
|
||||
self.handle = ManagedTorchModel(model, processor=processor)
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
|
||||
def detect(
|
||||
self,
|
||||
images: torch.Tensor,
|
||||
labels: list[str],
|
||||
*,
|
||||
box_threshold: float,
|
||||
text_threshold: float,
|
||||
nms_threshold: float,
|
||||
max_detections: int,
|
||||
fps: float,
|
||||
batch_size: int,
|
||||
) -> DetectionSequence:
|
||||
if not math.isfinite(fps) or fps <= 0:
|
||||
raise ValueError("fps must be finite and positive.")
|
||||
if not isinstance(batch_size, int) or batch_size < 1:
|
||||
raise ValueError("batch_size must be a positive integer.")
|
||||
frames = []
|
||||
pil_images = tensor_batch_to_pil(images)
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
for start in range(0, len(pil_images), batch_size):
|
||||
image_batch = pil_images[start : start + batch_size]
|
||||
text = [labels] * len(image_batch)
|
||||
inputs = self.processor(
|
||||
images=image_batch,
|
||||
text=text,
|
||||
return_tensors="pt",
|
||||
)
|
||||
inputs = move_inputs(inputs, device, floating_dtype=self.dtype)
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
outputs = model(**inputs)
|
||||
results = _post_process(
|
||||
self.processor,
|
||||
self.spec,
|
||||
outputs,
|
||||
inputs,
|
||||
labels,
|
||||
[(image.height, image.width) for image in image_batch],
|
||||
box_threshold,
|
||||
text_threshold,
|
||||
nms_threshold,
|
||||
max_detections,
|
||||
)
|
||||
if len(results) != len(image_batch):
|
||||
raise RuntimeError(
|
||||
f"{self.spec.model_id} returned {len(results)} result sets "
|
||||
f"for a batch of {len(image_batch)} images."
|
||||
)
|
||||
for offset, (image, result) in enumerate(
|
||||
zip(image_batch, results, strict=True)
|
||||
):
|
||||
frame_index = start + offset
|
||||
detections = result_to_detections(
|
||||
result,
|
||||
labels=labels,
|
||||
width=image.width,
|
||||
height=image.height,
|
||||
frame_index=frame_index,
|
||||
timestamp=frame_index / fps,
|
||||
source=self.spec.model_id,
|
||||
max_detections=max_detections,
|
||||
)
|
||||
frames.append(
|
||||
FrameDetections(
|
||||
frame_index=frame_index,
|
||||
timestamp=frame_index / fps,
|
||||
width=image.width,
|
||||
height=image.height,
|
||||
detections=detections,
|
||||
)
|
||||
)
|
||||
first = pil_images[0]
|
||||
return DetectionSequence(
|
||||
width=first.width,
|
||||
height=first.height,
|
||||
frames=tuple(frames),
|
||||
frame_count=len(frames),
|
||||
fps=fps,
|
||||
source=self.spec.model_id,
|
||||
metadata={"labels": labels, "model_family": self.spec.family},
|
||||
)
|
||||
|
||||
|
||||
def render_detections(
|
||||
images: torch.Tensor, detections: DetectionSequence
|
||||
) -> torch.Tensor:
|
||||
rendered = []
|
||||
for index, image in enumerate(tensor_batch_to_pil(images)):
|
||||
canvas = image.copy()
|
||||
draw = ImageDraw.Draw(canvas)
|
||||
frame = detections.frame(index)
|
||||
for detection in frame.detections if frame else ():
|
||||
color = deterministic_color(
|
||||
detection.track_id
|
||||
if detection.track_id is not None
|
||||
else detection.label or "object"
|
||||
)
|
||||
color = tuple(int(component) for component in color)
|
||||
x1, y1, x2, y2 = detection.bbox_xyxy
|
||||
draw.rectangle(
|
||||
(x1, y1, max(x1, x2 - 1), max(y1, y2 - 1)),
|
||||
outline=color,
|
||||
width=max(2, round(min(image.size) / 256)),
|
||||
)
|
||||
label = detection.label or "object"
|
||||
if detection.score is not None:
|
||||
label += f" {detection.score:.2f}"
|
||||
text_box = draw.textbbox((x1, y1), label)
|
||||
draw.rectangle(text_box, fill=color)
|
||||
draw.text((x1, y1), label, fill=(0, 0, 0))
|
||||
array = torch.from_numpy(np.asarray(canvas, dtype=np.float32).copy())
|
||||
rendered.append(array / 255.0)
|
||||
return torch.stack(rendered)
|
||||
|
||||
|
||||
def detection_box_masks(
|
||||
detections: DetectionSequence,
|
||||
) -> torch.Tensor:
|
||||
masks = torch.zeros(
|
||||
(detections.frame_count, detections.height, detections.width),
|
||||
dtype=torch.float32,
|
||||
)
|
||||
for frame in detections.frames:
|
||||
for detection in frame.detections:
|
||||
x1, y1, x2, y2 = detection.bbox_xyxy
|
||||
ix1, iy1 = int(x1), int(y1)
|
||||
ix2, iy2 = int(math.ceil(x2)), int(math.ceil(y2))
|
||||
masks[frame.frame_index, iy1:iy2, ix1:ix2] = 1.0
|
||||
return masks
|
||||
|
||||
|
||||
def _core_box(detection: Detection) -> dict[str, Any]:
|
||||
x1, y1, x2, y2 = detection.bbox_xyxy
|
||||
left, top = math.floor(x1), math.floor(y1)
|
||||
right, bottom = math.ceil(x2), math.ceil(y2)
|
||||
return {
|
||||
"x": left,
|
||||
"y": top,
|
||||
"width": right - left,
|
||||
"height": bottom - top,
|
||||
"label": detection.label,
|
||||
"score": detection.score,
|
||||
"metadata": {
|
||||
"frame_index": detection.frame_index,
|
||||
"label": detection.label,
|
||||
"score": detection.score,
|
||||
"source": detection.source,
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
def core_bounding_box_frames(
|
||||
detections: DetectionSequence,
|
||||
) -> list[list[dict[str, Any]]]:
|
||||
"""Return the nested per-frame convention used by core BOUNDING_BOX."""
|
||||
|
||||
frames = [[] for _index in range(detections.frame_count)]
|
||||
for frame in detections.frames:
|
||||
frames[frame.frame_index] = [
|
||||
_core_box(detection) for detection in frame.detections
|
||||
]
|
||||
return frames
|
||||
|
||||
|
||||
def core_bounding_boxes(detections: DetectionSequence) -> list[dict[str, Any]]:
|
||||
"""Return the flat metadata-rich BOUNDING_BOXES contract."""
|
||||
|
||||
result = []
|
||||
for frame in detections.frames:
|
||||
for detection in frame.detections:
|
||||
result.append(_core_box(detection))
|
||||
return result
|
||||
|
||||
|
||||
class VLMOpenVocabularyDetection(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"model": (tuple(MODEL_SPECS),),
|
||||
"labels": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "person, animal, vehicle",
|
||||
"tooltip": "Comma, semicolon, or newline-separated concepts.",
|
||||
},
|
||||
),
|
||||
"box_threshold": (
|
||||
"FLOAT",
|
||||
{"default": 0.3, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"text_threshold": (
|
||||
"FLOAT",
|
||||
{"default": 0.25, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"max_detections": (
|
||||
"INT",
|
||||
{"default": 100, "min": 1, "max": 1000},
|
||||
),
|
||||
"fps": (
|
||||
"FLOAT",
|
||||
{
|
||||
"default": 1.0,
|
||||
"min": 0.001,
|
||||
"max": 1000.0,
|
||||
"step": 0.001,
|
||||
"tooltip": (
|
||||
"Connect Get Video Components fps for video batches."
|
||||
),
|
||||
},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"nms_threshold": (
|
||||
"FLOAT",
|
||||
{"default": 0.5, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"precision": (("auto", "bfloat16", "float16", "float32"),),
|
||||
"batch_size": (
|
||||
"INT",
|
||||
{
|
||||
"default": 1,
|
||||
"min": 1,
|
||||
"max": 16,
|
||||
"tooltip": (
|
||||
"Frames per model call. Increase only when VRAM allows."
|
||||
),
|
||||
},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = (
|
||||
VLM_DETECTIONS,
|
||||
"STRING",
|
||||
"IMAGE",
|
||||
"MASK",
|
||||
"BOUNDING_BOX",
|
||||
"BOUNDING_BOXES",
|
||||
)
|
||||
RETURN_NAMES = (
|
||||
"detections",
|
||||
"json",
|
||||
"preview",
|
||||
"box_mask",
|
||||
"bounding_boxes",
|
||||
"bounding_boxes_with_metadata",
|
||||
)
|
||||
FUNCTION = "detect"
|
||||
CATEGORY = "VLM Nodes/Vision/Detection"
|
||||
DESCRIPTION = (
|
||||
"Detect text-specified objects with one portable interface. Outputs "
|
||||
"versioned detections, JSON, preview, box masks, and core boxes."
|
||||
)
|
||||
|
||||
def detect(
|
||||
self,
|
||||
image,
|
||||
model,
|
||||
labels,
|
||||
box_threshold,
|
||||
text_threshold,
|
||||
max_detections,
|
||||
fps,
|
||||
nms_threshold=0.5,
|
||||
precision="auto",
|
||||
batch_size=1,
|
||||
unload_after=False,
|
||||
):
|
||||
concepts = parse_labels(labels)
|
||||
fps_value = float(fps)
|
||||
batch_size_value = int(batch_size)
|
||||
if not math.isfinite(fps_value) or fps_value <= 0:
|
||||
raise ValueError("fps must be finite and positive.")
|
||||
if batch_size_value < 1:
|
||||
raise ValueError("batch_size must be a positive integer.")
|
||||
spec = MODEL_SPECS[model]
|
||||
predictor = self.get_or_create_model(
|
||||
(spec.model_id, precision),
|
||||
lambda: OpenVocabularyDetector(spec, precision),
|
||||
)
|
||||
try:
|
||||
detections = predictor.detect(
|
||||
image,
|
||||
concepts,
|
||||
box_threshold=box_threshold,
|
||||
text_threshold=text_threshold,
|
||||
nms_threshold=nms_threshold,
|
||||
max_detections=max_detections,
|
||||
fps=fps_value,
|
||||
batch_size=batch_size_value,
|
||||
)
|
||||
return (
|
||||
detections,
|
||||
detections.to_json(indent=2),
|
||||
render_detections(image, detections),
|
||||
detection_box_masks(detections),
|
||||
core_bounding_box_frames(detections),
|
||||
core_bounding_boxes(detections),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"VLMOpenVocabularyDetection": VLMOpenVocabularyDetection,
|
||||
}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"VLMOpenVocabularyDetection": "VLM Open-Vocabulary Detection",
|
||||
}
|
||||
+1825
File diff suppressed because it is too large
Load Diff
@@ -1,90 +0,0 @@
|
||||
from .joytagger import Models
|
||||
from PIL import Image
|
||||
import torch.amp.autocast_mode
|
||||
from pathlib import Path
|
||||
import torch
|
||||
import torchvision.transforms.functional as TVF
|
||||
from huggingface_hub import snapshot_download
|
||||
from torchvision import transforms
|
||||
import torch, auto_gptq
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
from auto_gptq.modeling._base import BaseGPTQForCausalLM
|
||||
from io import BytesIO
|
||||
from torchvision.transforms import ToPILImage
|
||||
|
||||
# Define your local directory where you want to save the files
|
||||
files_for_internlm = Path(__file__).resolve().parent / "files_for_internlm"
|
||||
|
||||
# Check if the directory exists, create if it doesn't (optional)
|
||||
files_for_internlm.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
class InternLMXComposer2QForCausalLM(BaseGPTQForCausalLM):
|
||||
layers_block_name = "model.layers"
|
||||
outside_layer_modules = [
|
||||
'vit', 'vision_proj', 'model.tok_embeddings', 'model.norm', 'output',
|
||||
]
|
||||
inside_layer_modules = [
|
||||
["attention.wqkv.linear"],
|
||||
["attention.wo.linear"],
|
||||
["feed_forward.w1.linear", "feed_forward.w3.linear"],
|
||||
["feed_forward.w2.linear"],
|
||||
]
|
||||
def download_internlm():
|
||||
# Ensure the correct behavior based on the existence of the local directory
|
||||
print(f"Target directory for download: {files_for_internlm}")
|
||||
|
||||
# Call snapshot_download with specified parameters
|
||||
path = snapshot_download(
|
||||
"internlm/internlm-xcomposer2-vl-7b-4bit", # Example repo_id
|
||||
local_dir=files_for_internlm,
|
||||
force_download=False, # Set to True if you always want to download, regardless of local copy
|
||||
local_files_only=False, # Set to False to allow downloading if not available locally
|
||||
local_dir_use_symlinks="auto" # or set to True/False based on your symlink preference
|
||||
)
|
||||
print(f"Model path: {path}")
|
||||
return path
|
||||
|
||||
class Internlm:
|
||||
def __init__(self):
|
||||
pass
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"question": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "",
|
||||
},
|
||||
),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
|
||||
FUNCTION = "internlm_chat"
|
||||
|
||||
CATEGORY = "VLM Nodes/Internlm"
|
||||
|
||||
def internlm_chat(self, image, question):
|
||||
model_path = download_internlm()
|
||||
print(f"Model path: {model_path}")
|
||||
model = InternLMXComposer2QForCausalLM.from_quantized(model_path , trust_remote_code=True, device="cuda:0").eval()
|
||||
|
||||
tokenizer = AutoTokenizer.from_pretrained(model_path , trust_remote_code=True)
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
temp_path = files_for_internlm / "temp.jpg"
|
||||
pil_image.save(temp_path)
|
||||
text = f'<ImageHere>{question}'
|
||||
with torch.cuda.amp.autocast():
|
||||
response, _ = model.chat(tokenizer, query=text, image=str(temp_path), history=[], do_sample=False)
|
||||
return (response, )
|
||||
|
||||
# A dictionary that contains all nodes you want to export with their names
|
||||
NODE_CLASS_MAPPINGS = {"Internlm": Internlm}
|
||||
|
||||
# A dictionary that contains the friendly/humanly readable titles for the nodes
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Internlm": "Internlm Node"}
|
||||
+120
-121
@@ -1,141 +1,140 @@
|
||||
from .joytagger import Models
|
||||
from PIL import Image
|
||||
import torch.amp.autocast_mode
|
||||
from pathlib import Path
|
||||
"""JoyTag image tagging with cached, ComfyUI-managed model weights."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torchvision.transforms.functional as TVF
|
||||
from huggingface_hub import snapshot_download
|
||||
from torchvision import transforms
|
||||
import os
|
||||
from PIL import Image
|
||||
|
||||
THRESHOLD = 0.4
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
inference_context,
|
||||
model_device,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
# Define your local directory where you want to save the files
|
||||
files_for_joytagger = Path(__file__).resolve().parent / "files_for_joytagger"
|
||||
|
||||
# Check if the directory exists, create if it doesn't (optional)
|
||||
files_for_joytagger.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
def download_joytag():
|
||||
# Ensure the correct behavior based on the existence of the local directory
|
||||
print(f"Target directory for download: {files_for_joytagger}")
|
||||
|
||||
# Call snapshot_download with specified parameters
|
||||
path = snapshot_download(
|
||||
"fancyfeast/joytag", # Example repo_id
|
||||
local_dir=files_for_joytagger,
|
||||
force_download=False, # Set to True if you always want to download, regardless of local copy
|
||||
local_files_only=False, # Set to False to allow downloading if not available locally
|
||||
local_dir_use_symlinks="auto" # or set to True/False based on your symlink preference
|
||||
)
|
||||
print(f"Model path: {path}")
|
||||
return path
|
||||
MODEL_ID = "fancyfeast/joytag"
|
||||
|
||||
|
||||
def prepare_image(image: Image.Image, target_size: int) -> torch.Tensor:
|
||||
# Pad image to square
|
||||
image_shape = image.size
|
||||
max_dim = max(image_shape)
|
||||
pad_left = (max_dim - image_shape[0]) // 2
|
||||
pad_top = (max_dim - image_shape[1]) // 2
|
||||
|
||||
padded_image = Image.new('RGB', (max_dim, max_dim), (255, 255, 255))
|
||||
padded_image.paste(image, (pad_left, pad_top))
|
||||
|
||||
# Resize image
|
||||
if max_dim != target_size:
|
||||
padded_image = padded_image.resize((target_size, target_size), Image.BICUBIC)
|
||||
|
||||
# Convert to tensor
|
||||
image_tensor = TVF.pil_to_tensor(padded_image) / 255.0
|
||||
|
||||
# Normalize
|
||||
image_tensor = TVF.normalize(image_tensor, mean=[0.48145466, 0.4578275, 0.40821073], std=[0.26862954, 0.26130258, 0.27577711])
|
||||
|
||||
return image_tensor
|
||||
width, height = image.size
|
||||
side = max(width, height)
|
||||
canvas = Image.new("RGB", (side, side), (255, 255, 255))
|
||||
canvas.paste(image.convert("RGB"), ((side - width) // 2, (side - height) // 2))
|
||||
if side != target_size:
|
||||
canvas = canvas.resize(
|
||||
(target_size, target_size), Image.Resampling.BICUBIC
|
||||
)
|
||||
array = np.asarray(canvas, dtype=np.float32) / 255.0
|
||||
tensor = torch.from_numpy(array.copy()).permute(2, 0, 1)
|
||||
mean = torch.tensor([0.48145466, 0.4578275, 0.40821073])[:, None, None]
|
||||
std = torch.tensor([0.26862954, 0.26130258, 0.27577711])[:, None, None]
|
||||
return (tensor - mean) / std
|
||||
|
||||
|
||||
def clean_tag(tag: str) -> str:
|
||||
return (
|
||||
tag.replace("(medium)", "")
|
||||
.replace("\\", "")
|
||||
.replace("m/", "")
|
||||
.replace("_", " ")
|
||||
.strip(" -")
|
||||
)
|
||||
|
||||
|
||||
# Extract and process the tags
|
||||
def process_tag(tag):
|
||||
tag = tag.replace("(medium)", "") # Remove (medium)
|
||||
tag = tag.replace("\\", "") # Remove \
|
||||
tag = tag.replace("m/", "") # Remove m/
|
||||
tag = tag.replace("-", "") # Remove -
|
||||
tag = tag.replace("_", " ") # Replace underscores with spaces
|
||||
tag = tag.strip() # Remove leading and trailing spaces
|
||||
return tag
|
||||
class JoyTagPredictor:
|
||||
def __init__(self):
|
||||
from .joytagger import Models
|
||||
|
||||
class Joytag:
|
||||
def __init__(self):
|
||||
pass
|
||||
path = snapshot_download(MODEL_ID, "joytag")
|
||||
model = Models.VisionModel.load_model(path, device=None).eval()
|
||||
self.tags = [
|
||||
line.strip()
|
||||
for line in (path / "top_tags.txt").read_text(
|
||||
encoding="utf-8"
|
||||
).splitlines()
|
||||
if line.strip()
|
||||
]
|
||||
self.dtype = torch_dtype("float16")
|
||||
self.handle = ManagedTorchModel(model)
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"tag_number": ("INT", {
|
||||
"default": 1,
|
||||
"min": 1, #Minimum value
|
||||
"max": 100, #Maximum value
|
||||
"step": 1, #Slider's step
|
||||
"display": "number" # Cosmetic only: display as "number" or "slider"
|
||||
}),
|
||||
},
|
||||
}
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.tags = []
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
def predict(self, images, count: int, threshold: float):
|
||||
results = []
|
||||
for image in tensor_batch_to_pil(images):
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
tensor = prepare_image(image, model.image_size).unsqueeze(0).to(device)
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
predictions = model({"image": tensor})["tags"].sigmoid()[0]
|
||||
scores = predictions.float().cpu()
|
||||
ranked = torch.argsort(scores, descending=True).tolist()
|
||||
selected = [
|
||||
index
|
||||
for index in ranked
|
||||
if scores[index].item() >= float(threshold)
|
||||
][: int(count)]
|
||||
# Always return up to tag_number useful results, even when the
|
||||
# threshold is deliberately high.
|
||||
if not selected:
|
||||
selected = ranked[: int(count)]
|
||||
tags = [clean_tag(self.tags[index]) for index in selected]
|
||||
results.append(", ".join(tag for tag in tags if tag))
|
||||
return batch_text(results)
|
||||
|
||||
FUNCTION = "tags"
|
||||
|
||||
CATEGORY = "VLM Nodes/JoyTag"
|
||||
class Joytag(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"tag_number": (
|
||||
"INT",
|
||||
{
|
||||
"default": 20,
|
||||
"min": 1,
|
||||
"max": 100,
|
||||
"step": 1,
|
||||
"display": "number",
|
||||
},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"threshold": (
|
||||
"FLOAT",
|
||||
{"default": 0.4, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
def tags(self, image, tag_number):
|
||||
path = download_joytag()
|
||||
print(f"Model path: {path}")
|
||||
model = Models.VisionModel.load_model(Path(path), device='cuda')
|
||||
model.eval()
|
||||
with open(Path(path) / 'top_tags.txt', 'r') as f:
|
||||
top_tags = [line.strip() for line in f.readlines() if line.strip()]
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "tags"
|
||||
CATEGORY = "VLM Nodes/Vision/Tagging"
|
||||
|
||||
@torch.no_grad()
|
||||
def predict(image: Image.Image):
|
||||
image_tensor = prepare_image(image, model.image_size)
|
||||
batch = {
|
||||
'image': image_tensor.unsqueeze(0).to('cuda'),
|
||||
}
|
||||
|
||||
with torch.amp.autocast_mode.autocast('cuda', enabled=True):
|
||||
preds = model(batch)
|
||||
tag_preds = preds['tags'].sigmoid().cpu()
|
||||
|
||||
scores = {top_tags[i]: tag_preds[0][i] for i in range(len(top_tags))}
|
||||
predicted_tags = [tag for tag, score in scores.items() if score > THRESHOLD]
|
||||
tag_string = ', '.join(predicted_tags)
|
||||
|
||||
return tag_string, scores
|
||||
|
||||
image = transforms.ToPILImage()(image[0].permute(2, 0, 1))
|
||||
_, scores = predict(image)
|
||||
|
||||
# Get the top 50 tag and score pairs
|
||||
top_tags_scores = sorted(scores.items(), key=lambda x: x[1], reverse=True)[:tag_number]
|
||||
|
||||
# Extract the tags from the pairs
|
||||
top_tags_processed = [process_tag(tag) for tag, _ in top_tags_scores]
|
||||
|
||||
top_tags_full = [tag for tag in top_tags_processed if tag]
|
||||
|
||||
# Concatenate the tags with a comma separator
|
||||
top_50_tags_string = ', '.join(top_tags_full)
|
||||
|
||||
return (top_50_tags_string, )
|
||||
def tags(
|
||||
self,
|
||||
image,
|
||||
tag_number,
|
||||
threshold=0.4,
|
||||
unload_after=False,
|
||||
):
|
||||
predictor = self.get_or_create_model(MODEL_ID, JoyTagPredictor)
|
||||
try:
|
||||
return (
|
||||
predictor.predict(image, tag_number, threshold),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
# A dictionary that contains all nodes you want to export with their names
|
||||
NODE_CLASS_MAPPINGS = {"Joytag": Joytag}
|
||||
|
||||
# A dictionary that contains the friendly/humanly readable titles for the nodes
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Joytag": "Joytag Node"}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Joytag": "JoyTag"}
|
||||
|
||||
@@ -2,7 +2,6 @@ import json
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
import torch
|
||||
import torch.backends.cuda
|
||||
import torch.nn as nn
|
||||
import torch.nn.functional as F
|
||||
import torchvision
|
||||
@@ -211,9 +210,8 @@ class FastCLIPAttention2(nn.Module):
|
||||
v_states = v_states.view(bsz, src_len, self.num_heads, self.head_dim).transpose(1, 2) # (bsz, num_heads, src_len, head_dim)
|
||||
|
||||
# Performs scale of query_states, attention, and softmax
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False):
|
||||
x = F.scaled_dot_product_attention(q_states, k_states, v_states) # (bsz, num_heads, tgt_len, head_dim)
|
||||
x = x.transpose(1, 2).contiguous().view(bsz, tgt_len, embed_dim) # (bsz, tgt_len, embed_dim)
|
||||
x = F.scaled_dot_product_attention(q_states, k_states, v_states) # (bsz, num_heads, tgt_len, head_dim)
|
||||
x = x.transpose(1, 2).contiguous().view(bsz, tgt_len, embed_dim) # (bsz, tgt_len, embed_dim)
|
||||
|
||||
# Projection
|
||||
x = self.out_proj(x) # (bsz, tgt_len, out_dim)
|
||||
@@ -865,9 +863,8 @@ class ViTBlock(nn.Module):
|
||||
k_states = qkv_states[1].view(bsz, src_len, self.num_heads, embed_dim // self.num_heads).transpose(1, 2) # (bsz, num_heads, src_len, embed_dim // num_heads)
|
||||
v_states = qkv_states[2].view(bsz, src_len, self.num_heads, embed_dim // self.num_heads).transpose(1, 2) # (bsz, num_heads, src_len, embed_dim // num_heads)
|
||||
|
||||
with torch.backends.cuda.sdp_kernel(enable_math=False):
|
||||
out = F.scaled_dot_product_attention(q_states, k_states, v_states) # (bsz, num_heads, tgt_len, head_dim)
|
||||
out = out.transpose(1, 2).contiguous().view(bsz, src_len, embed_dim) # (bsz, tgt_len, embed_dim)
|
||||
out = F.scaled_dot_product_attention(q_states, k_states, v_states) # (bsz, num_heads, tgt_len, head_dim)
|
||||
out = out.transpose(1, 2).contiguous().view(bsz, src_len, embed_dim) # (bsz, tgt_len, embed_dim)
|
||||
|
||||
out = self.out_proj(out)
|
||||
|
||||
|
||||
@@ -0,0 +1,124 @@
|
||||
"""Kosmos-2 grounding/caption node with lazy, Comfy-managed loading."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import torch
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
inference_context,
|
||||
model_device,
|
||||
move_inputs,
|
||||
require_module,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
MODEL_ID = "microsoft/kosmos-2-patch14-224"
|
||||
|
||||
|
||||
class KosmosModelPredictor:
|
||||
def __init__(self):
|
||||
transformers = require_module("transformers")
|
||||
model_path = snapshot_download(
|
||||
MODEL_ID, "kosmos2", ignore_patterns=["*.bin"]
|
||||
)
|
||||
self.dtype = torch_dtype("bfloat16")
|
||||
model_class = getattr(
|
||||
transformers,
|
||||
"Kosmos2ForConditionalGeneration",
|
||||
getattr(transformers, "AutoModelForImageTextToText", None),
|
||||
)
|
||||
if model_class is None:
|
||||
raise RuntimeError(
|
||||
"This Transformers version does not include Kosmos-2 support."
|
||||
)
|
||||
model = model_class.from_pretrained(
|
||||
model_path, torch_dtype=self.dtype
|
||||
).eval()
|
||||
self.processor = transformers.AutoProcessor.from_pretrained(model_path)
|
||||
self.handle = ManagedTorchModel(model, processor=self.processor)
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
def generate(self, images, text, max_new_tokens):
|
||||
results = []
|
||||
for image in tensor_batch_to_pil(images):
|
||||
prompt = f"<grounding>{text.strip()}"
|
||||
inputs = self.processor(
|
||||
text=prompt, images=image, return_tensors="pt"
|
||||
)
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
inputs = move_inputs(inputs, device)
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
output = model.generate(
|
||||
**inputs,
|
||||
use_cache=True,
|
||||
max_new_tokens=int(max_new_tokens),
|
||||
)
|
||||
decoded = self.processor.batch_decode(
|
||||
output, skip_special_tokens=True
|
||||
)[0]
|
||||
post_process = getattr(
|
||||
self.processor, "post_process_generation", None
|
||||
)
|
||||
if callable(post_process):
|
||||
processed, _entities = post_process(decoded)
|
||||
else:
|
||||
processed = decoded
|
||||
if processed.startswith(text):
|
||||
processed = processed[len(text) :].lstrip(": \n")
|
||||
results.append(processed.strip())
|
||||
return batch_text(results)
|
||||
|
||||
|
||||
class Kosmos2model(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"text_input": (
|
||||
"STRING",
|
||||
{"multiline": True, "default": "Describe the image."},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 128, "min": 1, "max": 2048},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "new_model_generate_predictions"
|
||||
CATEGORY = "VLM Nodes/Legacy/Model Loaders"
|
||||
|
||||
def new_model_generate_predictions(
|
||||
self,
|
||||
image,
|
||||
text_input,
|
||||
max_new_tokens=128,
|
||||
unload_after=False,
|
||||
):
|
||||
predictor = self.get_or_create_model(
|
||||
MODEL_ID, KosmosModelPredictor
|
||||
)
|
||||
try:
|
||||
return (
|
||||
predictor.generate(image, text_input, max_new_tokens),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"Kosmos2model": Kosmos2model}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Kosmos2model": "Kosmos-2"}
|
||||
+544
-145
@@ -1,74 +1,198 @@
|
||||
"""llama.cpp multimodal nodes with lazy loading and owned GPU cleanup."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Any
|
||||
|
||||
import folder_paths
|
||||
import os
|
||||
from io import BytesIO
|
||||
from llama_cpp import Llama
|
||||
from llama_cpp.llama_chat_format import Llava15ChatHandler
|
||||
import base64
|
||||
from torchvision.transforms import ToPILImage
|
||||
|
||||
from .runtime import (
|
||||
LLAMA_VISION_HANDLER_CHOICES,
|
||||
LlamaHandle,
|
||||
LlavaClipConfig,
|
||||
batch_text,
|
||||
close_handle,
|
||||
default_llama_threads,
|
||||
image_data_uri,
|
||||
llama_chat_content,
|
||||
llama_runtime_input_types,
|
||||
llama_runtime_options,
|
||||
resolve_model_path,
|
||||
tensor_batch_to_pil,
|
||||
unwrap_llm,
|
||||
)
|
||||
|
||||
|
||||
supported_LLava_extensions = set(['.gguf'])
|
||||
def _clip_factory(clip: Any):
|
||||
if isinstance(clip, LlavaClipConfig):
|
||||
return clip.create
|
||||
if callable(getattr(clip, "create", None)):
|
||||
return clip.create
|
||||
# Compatibility with workflows that pass a pre-created llama.cpp handler.
|
||||
return lambda: clip
|
||||
|
||||
|
||||
def _make_handle(
|
||||
ckpt_name: str,
|
||||
max_ctx: int,
|
||||
gpu_layers: int,
|
||||
n_threads: int,
|
||||
clip: Any,
|
||||
*,
|
||||
seed: int = 42,
|
||||
runtime_options: dict[str, Any] | None = None,
|
||||
) -> LlamaHandle:
|
||||
options = dict(runtime_options or {})
|
||||
if isinstance(clip, LlavaClipConfig):
|
||||
options.setdefault("projector_path", clip.model_path)
|
||||
return LlamaHandle(
|
||||
resolve_model_path(ckpt_name),
|
||||
n_ctx=max_ctx,
|
||||
n_gpu_layers=gpu_layers,
|
||||
n_threads=n_threads,
|
||||
chat_handler_factory=_clip_factory(clip),
|
||||
seed=seed,
|
||||
**options,
|
||||
)
|
||||
|
||||
|
||||
def _vision_messages(system_msg: str, prompt: str, data_uri: str):
|
||||
return [
|
||||
{"role": "system", "content": system_msg},
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "image_url", "image_url": {"url": data_uri}},
|
||||
{"type": "text", "text": prompt},
|
||||
],
|
||||
},
|
||||
]
|
||||
|
||||
|
||||
def _run_batch(
|
||||
image,
|
||||
model,
|
||||
*,
|
||||
system_msg: str,
|
||||
prompt: str,
|
||||
**generation: Any,
|
||||
) -> str:
|
||||
llm = unwrap_llm(model)
|
||||
responses = []
|
||||
for pil_image in tensor_batch_to_pil(image):
|
||||
response = llm.create_chat_completion(
|
||||
messages=_vision_messages(system_msg, prompt, image_data_uri(pil_image)),
|
||||
**generation,
|
||||
)
|
||||
responses.append(llama_chat_content(response))
|
||||
return batch_text(responses)
|
||||
|
||||
|
||||
try:
|
||||
folder_paths.folder_names_and_paths["LLavacheckpoints"] = (folder_paths.folder_names_and_paths["LLavacheckpoints"][0], supported_LLava_extensions)
|
||||
except:
|
||||
# check if LLavacheckpoints exists otherwise create
|
||||
if not os.path.isdir(os.path.join(folder_paths.models_dir, "LLavacheckpoints")):
|
||||
os.mkdir(os.path.join(folder_paths.models_dir, "LLavacheckpoints"))
|
||||
|
||||
folder_paths.folder_names_and_paths["LLavacheckpoints"] = ([os.path.join(folder_paths.models_dir, "LLavacheckpoints")], supported_LLava_extensions)
|
||||
|
||||
class LLavaLoader:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {"required": {
|
||||
"ckpt_name": (folder_paths.get_filename_list("LLavacheckpoints"), ),
|
||||
"max_ctx": ("INT", {"default": 2048, "min": 300, "max": 100000, "step": 64}),
|
||||
"gpu_layers": ("INT", {"default": 27, "min": 0, "max": 100, "step": 1}),
|
||||
"n_threads": ("INT", {"default": 8, "min": 1, "max": 100, "step": 1}),
|
||||
"clip": ("CUSTOM", {"default": ""}),
|
||||
}}
|
||||
|
||||
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"ckpt_name": (folder_paths.get_filename_list("LLavacheckpoints"),),
|
||||
"max_ctx": (
|
||||
"INT",
|
||||
{"default": 4096, "min": 128, "max": 131072, "step": 64},
|
||||
),
|
||||
"gpu_layers": (
|
||||
"INT",
|
||||
{"default": -1, "min": -1, "max": 1000, "step": 1},
|
||||
),
|
||||
"n_threads": (
|
||||
"INT",
|
||||
{
|
||||
"default": default_llama_threads(),
|
||||
"min": 1,
|
||||
"max": 256,
|
||||
"step": 1,
|
||||
},
|
||||
),
|
||||
"clip": ("CUSTOM", {"default": ""}),
|
||||
},
|
||||
"optional": llama_runtime_input_types(),
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("CUSTOM",)
|
||||
RETURN_NAMES = ("model",)
|
||||
FUNCTION = "load_llava_checkpoint"
|
||||
|
||||
CATEGORY = "VLM Nodes/LLava"
|
||||
def load_llava_checkpoint(self, ckpt_name, max_ctx, gpu_layers, n_threads, clip ):
|
||||
ckpt_path = folder_paths.get_full_path("LLavacheckpoints", ckpt_name)
|
||||
llm = Llama(model_path = ckpt_path, chat_handler=clip,offload_kqv=True, f16_kv=True, use_mlock=False, embedding=False, n_batch=1024, last_n_tokens_size=1024, verbose=True, seed=42, n_ctx = max_ctx, n_gpu_layers=gpu_layers, n_threads=n_threads, logits_all=True, echo=False)
|
||||
return (llm, )
|
||||
|
||||
|
||||
def load_llava_checkpoint(
|
||||
self,
|
||||
ckpt_name,
|
||||
max_ctx,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
clip,
|
||||
n_batch=512,
|
||||
n_ubatch=512,
|
||||
flash_attention="Auto",
|
||||
use_mmap=True,
|
||||
split_mode="Layer",
|
||||
main_gpu=0,
|
||||
tensor_split="",
|
||||
):
|
||||
# The GGUF and mmproj are loaded only when a sampler actually executes.
|
||||
return (
|
||||
_make_handle(
|
||||
ckpt_name,
|
||||
max_ctx,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
clip,
|
||||
runtime_options=llama_runtime_options(
|
||||
n_batch=n_batch,
|
||||
n_ubatch=n_ubatch,
|
||||
flash_attention=flash_attention,
|
||||
use_mmap=use_mmap,
|
||||
split_mode=split_mode,
|
||||
main_gpu=main_gpu,
|
||||
tensor_split=tensor_split,
|
||||
),
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
class LlavaClipLoader:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {"required": {
|
||||
"clip_name": (folder_paths.get_filename_list("LLavacheckpoints"), ),
|
||||
}}
|
||||
|
||||
RETURN_TYPES = ("CUSTOM", )
|
||||
RETURN_NAMES = ("clip", )
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"clip_name": (folder_paths.get_filename_list("LLavacheckpoints"),),
|
||||
},
|
||||
"optional": {
|
||||
"handler": (
|
||||
list(LLAMA_VISION_HANDLER_CHOICES),
|
||||
{"default": "Auto (GGUF chat template)"},
|
||||
),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("CUSTOM",)
|
||||
RETURN_NAMES = ("clip",)
|
||||
FUNCTION = "load_clip_checkpoint"
|
||||
|
||||
CATEGORY = "VLM Nodes/LLava"
|
||||
def load_clip_checkpoint(self, clip_name):
|
||||
clip_path = folder_paths.get_full_path("LLavacheckpoints", clip_name)
|
||||
clip = Llava15ChatHandler(clip_model_path = clip_path, verbose=False)
|
||||
return (clip, )
|
||||
|
||||
class LLavaSamplerSimple:
|
||||
def __init__(self):
|
||||
pass
|
||||
|
||||
def load_clip_checkpoint(self, clip_name, handler="LLaVA 1.5"):
|
||||
return (LlavaClipConfig(resolve_model_path(clip_name), handler),)
|
||||
|
||||
|
||||
class LLavaSamplerSimple:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"prompt": ("STRING",{"forceInput": True} ),
|
||||
"prompt": ("STRING", {"default": "", "multiline": True}),
|
||||
"model": ("CUSTOM", {"default": ""}),
|
||||
"temperature": ("FLOAT", {"default": 0.1, "min": 0.01, "max": 1.0, "step": 0.01}),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.1, "min": 0.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
@@ -77,62 +201,62 @@ class LLavaSamplerSimple:
|
||||
CATEGORY = "VLM Nodes/LLava"
|
||||
|
||||
def generate_text(self, image, prompt, model, temperature):
|
||||
|
||||
|
||||
# Assuming 'image' is a PyTorch tensor of shape [C, H, W]
|
||||
# Convert the PyTorch tensor to a PIL image
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
|
||||
# Convert the PIL image to a bytes buffer
|
||||
buffer = BytesIO()
|
||||
pil_image.save(buffer, format="JPEG") # You can change the format if needed
|
||||
|
||||
# Get the bytes from the buffer
|
||||
image_bytes = buffer.getvalue()
|
||||
|
||||
# Encode the bytes to base64
|
||||
base64_string = f"data:image/jpeg;base64,{base64.b64encode(image_bytes).decode('utf-8')}"
|
||||
|
||||
# Now, `base64_string` contains the base64-encoded string of the image
|
||||
|
||||
llm = model
|
||||
response = llm.create_chat_completion(
|
||||
messages = [
|
||||
{"role": "system", "content": "You are an assistant who perfectly describes images."},
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "image_url", "image_url": {"url" : base64_string}},
|
||||
{"type" : "text", "text": f"{prompt}"}
|
||||
]
|
||||
}
|
||||
|
||||
],
|
||||
temperature = temperature,
|
||||
return (
|
||||
_run_batch(
|
||||
image,
|
||||
model,
|
||||
system_msg="You are an assistant who accurately describes images.",
|
||||
prompt=prompt,
|
||||
temperature=temperature,
|
||||
),
|
||||
)
|
||||
|
||||
return (f"{response['choices'][0]['message']['content']}", )
|
||||
|
||||
class LLavaSamplerAdvanced:
|
||||
def __init__(self):
|
||||
pass
|
||||
|
||||
|
||||
class LLavaSamplerAdvanced:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"system_msg": ("STRING",{"default" : "You are an assistant who perfectly describes images."}),
|
||||
"prompt": ("STRING",{"forceInput": True, "default": ""}),
|
||||
"system_msg": (
|
||||
"STRING",
|
||||
{
|
||||
"default": (
|
||||
"You are an assistant who accurately describes images."
|
||||
)
|
||||
},
|
||||
),
|
||||
"prompt": (
|
||||
"STRING",
|
||||
{"default": "", "multiline": True},
|
||||
),
|
||||
"model": ("CUSTOM", {"default": ""}),
|
||||
"max_tokens": ("INT", {"default": 512, "min": 1, "max": 2048, "step": 1}),
|
||||
"temperature": ("FLOAT", {"default": 0.1, "min": 0.01, "max": 1.0, "step": 0.01}),
|
||||
"top_p": ("FLOAT", {"default": 0.95, "min": 0.1, "max": 1.0, "step": 0.01}),
|
||||
"top_k": ("INT", {"default": 40, "step": 1}),
|
||||
"frequency_penalty": ("FLOAT", {"default": 0.0, "step": 0.01}),
|
||||
"presence_penalty": ("FLOAT", {"default": 0.0, "step": 0.01}),
|
||||
"repeat_penalty": ("FLOAT", {"default": 1.1, "step": 0.01}),
|
||||
"seed": ("INT", {"default": 42, "step":1})
|
||||
"max_tokens": (
|
||||
"INT",
|
||||
{"default": 512, "min": 1, "max": 8192, "step": 1},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.1, "min": 0.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.95, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"top_k": ("INT", {"default": 40, "min": 0, "step": 1}),
|
||||
"frequency_penalty": (
|
||||
"FLOAT",
|
||||
{"default": 0.0, "min": -2.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"presence_penalty": (
|
||||
"FLOAT",
|
||||
{"default": 0.0, "min": -2.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"repeat_penalty": (
|
||||
"FLOAT",
|
||||
{"default": 1.1, "min": 0.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"seed": ("INT", {"default": 42, "step": 1}),
|
||||
}
|
||||
}
|
||||
|
||||
@@ -140,61 +264,336 @@ class LLavaSamplerAdvanced:
|
||||
FUNCTION = "generate_text_advanced"
|
||||
CATEGORY = "VLM Nodes/LLava"
|
||||
|
||||
def generate_text_advanced(self, image, system_msg, prompt, model, max_tokens, temperature, top_p, frequency_penalty, presence_penalty, repeat_penalty, top_k,seed):
|
||||
|
||||
# Assuming 'image' is a PyTorch tensor of shape [C, H, W]
|
||||
# Convert the PyTorch tensor to a PIL image
|
||||
pil_image = ToPILImage()(image[0].permute(2, 0, 1))
|
||||
|
||||
# Convert the PIL image to a bytes buffer
|
||||
buffer = BytesIO()
|
||||
pil_image.save(buffer, format="JPEG") # You can change the format if needed
|
||||
|
||||
# Get the bytes from the buffer
|
||||
image_bytes = buffer.getvalue()
|
||||
|
||||
# Encode the bytes to base64
|
||||
base64_string = f"data:image/jpeg;base64,{base64.b64encode(image_bytes).decode('utf-8')}"
|
||||
|
||||
# Now, `base64_string` contains the base64-encoded string of the image
|
||||
|
||||
llm = model
|
||||
response = llm.create_chat_completion(
|
||||
messages = [
|
||||
{"role": "system", "content": system_msg},
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "image_url", "image_url": {"url" : base64_string}},
|
||||
{"type" : "text", "text": f"{prompt}"}
|
||||
]
|
||||
}
|
||||
|
||||
],
|
||||
max_tokens = max_tokens,
|
||||
temperature = temperature,
|
||||
top_p = top_p,
|
||||
top_k = top_k,
|
||||
frequency_penalty = frequency_penalty,
|
||||
presence_penalty = presence_penalty,
|
||||
repeat_penalty = repeat_penalty,
|
||||
seed=seed
|
||||
|
||||
def generate_text_advanced(
|
||||
self,
|
||||
image,
|
||||
system_msg,
|
||||
prompt,
|
||||
model,
|
||||
max_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
top_k,
|
||||
frequency_penalty,
|
||||
presence_penalty,
|
||||
repeat_penalty,
|
||||
seed,
|
||||
):
|
||||
return (
|
||||
_run_batch(
|
||||
image,
|
||||
model,
|
||||
system_msg=system_msg,
|
||||
prompt=prompt,
|
||||
max_tokens=max_tokens,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
top_k=top_k,
|
||||
frequency_penalty=frequency_penalty,
|
||||
presence_penalty=presence_penalty,
|
||||
repeat_penalty=repeat_penalty,
|
||||
seed=seed,
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
return (f"{response['choices'][0]['message']['content']}", )
|
||||
class _CachedLlavaBase:
|
||||
def __init__(self):
|
||||
self._handle = None
|
||||
self._key = None
|
||||
|
||||
def _model(
|
||||
self,
|
||||
ckpt_name,
|
||||
clip_name,
|
||||
max_ctx,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
seed=42,
|
||||
handler="LLaVA 1.5",
|
||||
**runtime_options,
|
||||
):
|
||||
key = (
|
||||
ckpt_name,
|
||||
clip_name,
|
||||
int(max_ctx),
|
||||
int(gpu_layers),
|
||||
int(n_threads),
|
||||
int(seed),
|
||||
handler,
|
||||
tuple(sorted(runtime_options.items())),
|
||||
)
|
||||
if self._handle is None or self._key != key:
|
||||
close_handle(self._handle)
|
||||
clip = LlavaClipConfig(resolve_model_path(clip_name), handler)
|
||||
self._handle = _make_handle(
|
||||
ckpt_name,
|
||||
max_ctx,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
clip,
|
||||
seed=seed,
|
||||
runtime_options=runtime_options,
|
||||
)
|
||||
self._key = key
|
||||
return self._handle
|
||||
|
||||
def _maybe_unload(self, unload):
|
||||
if unload:
|
||||
close_handle(self._handle)
|
||||
self._handle = None
|
||||
self._key = None
|
||||
|
||||
|
||||
class LLavaOptionalMemoryFreeSimple(_CachedLlavaBase):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"ckpt_name": (folder_paths.get_filename_list("LLavacheckpoints"),),
|
||||
"clip_name": (folder_paths.get_filename_list("LLavacheckpoints"),),
|
||||
"max_ctx": (
|
||||
"INT",
|
||||
{"default": 4096, "min": 128, "max": 131072, "step": 64},
|
||||
),
|
||||
"gpu_layers": (
|
||||
"INT",
|
||||
{"default": -1, "min": -1, "max": 1000, "step": 1},
|
||||
),
|
||||
"n_threads": (
|
||||
"INT",
|
||||
{
|
||||
"default": default_llama_threads(),
|
||||
"min": 1,
|
||||
"max": 256,
|
||||
"step": 1,
|
||||
},
|
||||
),
|
||||
"image": ("IMAGE",),
|
||||
"prompt": ("STRING", {"default": "", "multiline": True}),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.1, "min": 0.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"unload": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
"optional": {
|
||||
"handler": (
|
||||
list(LLAMA_VISION_HANDLER_CHOICES),
|
||||
{"default": "Auto (GGUF chat template)"},
|
||||
),
|
||||
**llama_runtime_input_types(),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "generate_text"
|
||||
CATEGORY = "VLM Nodes/LLava"
|
||||
|
||||
def generate_text(
|
||||
self,
|
||||
ckpt_name,
|
||||
clip_name,
|
||||
max_ctx,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
image,
|
||||
prompt,
|
||||
temperature,
|
||||
unload,
|
||||
handler="LLaVA 1.5",
|
||||
n_batch=512,
|
||||
n_ubatch=512,
|
||||
flash_attention="Auto",
|
||||
use_mmap=True,
|
||||
split_mode="Layer",
|
||||
main_gpu=0,
|
||||
tensor_split="",
|
||||
):
|
||||
options = llama_runtime_options(
|
||||
n_batch=n_batch,
|
||||
n_ubatch=n_ubatch,
|
||||
flash_attention=flash_attention,
|
||||
use_mmap=use_mmap,
|
||||
split_mode=split_mode,
|
||||
main_gpu=main_gpu,
|
||||
tensor_split=tensor_split,
|
||||
)
|
||||
model = self._model(
|
||||
ckpt_name,
|
||||
clip_name,
|
||||
max_ctx,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
handler=handler,
|
||||
**options,
|
||||
)
|
||||
try:
|
||||
result = _run_batch(
|
||||
image,
|
||||
model,
|
||||
system_msg="You are an assistant who accurately describes images.",
|
||||
prompt=prompt,
|
||||
temperature=temperature,
|
||||
)
|
||||
return (result,)
|
||||
finally:
|
||||
self._maybe_unload(unload)
|
||||
|
||||
|
||||
class LLavaOptionalMemoryFreeAdvanced(_CachedLlavaBase):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
required = {
|
||||
"ckpt_name": (folder_paths.get_filename_list("LLavacheckpoints"),),
|
||||
"clip_name": (folder_paths.get_filename_list("LLavacheckpoints"),),
|
||||
"max_ctx": (
|
||||
"INT",
|
||||
{"default": 4096, "min": 128, "max": 131072, "step": 64},
|
||||
),
|
||||
"gpu_layers": (
|
||||
"INT",
|
||||
{"default": -1, "min": -1, "max": 1000, "step": 1},
|
||||
),
|
||||
"n_threads": (
|
||||
"INT",
|
||||
{
|
||||
"default": default_llama_threads(),
|
||||
"min": 1,
|
||||
"max": 256,
|
||||
"step": 1,
|
||||
},
|
||||
),
|
||||
"image": ("IMAGE",),
|
||||
"system_msg": (
|
||||
"STRING",
|
||||
{"default": ("You are an assistant who accurately describes images.")},
|
||||
),
|
||||
"prompt": ("STRING", {"default": "", "multiline": True}),
|
||||
"max_tokens": (
|
||||
"INT",
|
||||
{"default": 512, "min": 1, "max": 8192, "step": 1},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.1, "min": 0.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.95, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"top_k": ("INT", {"default": 40, "min": 0, "step": 1}),
|
||||
"frequency_penalty": (
|
||||
"FLOAT",
|
||||
{"default": 0.0, "min": -2.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"presence_penalty": (
|
||||
"FLOAT",
|
||||
{"default": 0.0, "min": -2.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"repeat_penalty": (
|
||||
"FLOAT",
|
||||
{"default": 1.1, "min": 0.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"seed": ("INT", {"default": 42, "step": 1}),
|
||||
"unload": ("BOOLEAN", {"default": False}),
|
||||
}
|
||||
return {
|
||||
"required": required,
|
||||
"optional": {
|
||||
"handler": (
|
||||
list(LLAMA_VISION_HANDLER_CHOICES),
|
||||
{"default": "Auto (GGUF chat template)"},
|
||||
),
|
||||
**llama_runtime_input_types(),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "generate_text_advanced"
|
||||
CATEGORY = "VLM Nodes/LLava"
|
||||
|
||||
def generate_text_advanced(
|
||||
self,
|
||||
ckpt_name,
|
||||
clip_name,
|
||||
max_ctx,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
image,
|
||||
system_msg,
|
||||
prompt,
|
||||
max_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
top_k,
|
||||
frequency_penalty,
|
||||
presence_penalty,
|
||||
repeat_penalty,
|
||||
seed,
|
||||
unload,
|
||||
handler="LLaVA 1.5",
|
||||
n_batch=512,
|
||||
n_ubatch=512,
|
||||
flash_attention="Auto",
|
||||
use_mmap=True,
|
||||
split_mode="Layer",
|
||||
main_gpu=0,
|
||||
tensor_split="",
|
||||
):
|
||||
options = llama_runtime_options(
|
||||
n_batch=n_batch,
|
||||
n_ubatch=n_ubatch,
|
||||
flash_attention=flash_attention,
|
||||
use_mmap=use_mmap,
|
||||
split_mode=split_mode,
|
||||
main_gpu=main_gpu,
|
||||
tensor_split=tensor_split,
|
||||
)
|
||||
model = self._model(
|
||||
ckpt_name,
|
||||
clip_name,
|
||||
max_ctx,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
seed,
|
||||
handler,
|
||||
**options,
|
||||
)
|
||||
try:
|
||||
result = _run_batch(
|
||||
image,
|
||||
model,
|
||||
system_msg=system_msg,
|
||||
prompt=prompt,
|
||||
max_tokens=max_tokens,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
top_k=top_k,
|
||||
frequency_penalty=frequency_penalty,
|
||||
presence_penalty=presence_penalty,
|
||||
repeat_penalty=repeat_penalty,
|
||||
seed=seed,
|
||||
)
|
||||
return (result,)
|
||||
finally:
|
||||
self._maybe_unload(unload)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"LLava Loader Simple": LLavaLoader,
|
||||
"LLavaSamplerSimple": LLavaSamplerSimple,
|
||||
"LlavaClipLoader": LlavaClipLoader,
|
||||
"LLavaSamplerAdvanced": LLavaSamplerAdvanced
|
||||
"LLavaSamplerAdvanced": LLavaSamplerAdvanced,
|
||||
"LLavaOptionalMemoryFreeSimple": LLavaOptionalMemoryFreeSimple,
|
||||
"LLavaOptionalMemoryFreeAdvanced": LLavaOptionalMemoryFreeAdvanced,
|
||||
}
|
||||
# A dictionary that contains the friendly/humanly readable titles for the nodes
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"LLava Loader Simple": "LLava Loader Simple",
|
||||
"LLavaSamplerSimple": "LLava Sampler Simple",
|
||||
"LlavaClipLoader": "Llava Clip Loader",
|
||||
"LLavaSamplerAdvanced": "LLava Sampler Advanced"
|
||||
"LLava Loader Simple": "LLaVA Loader",
|
||||
"LLavaSamplerSimple": "LLaVA Sampler",
|
||||
"LlavaClipLoader": "LLaVA Vision Projector Loader",
|
||||
"LLavaSamplerAdvanced": "LLaVA Sampler (Advanced)",
|
||||
"LLavaOptionalMemoryFreeSimple": "LLaVA (Managed Cache)",
|
||||
"LLavaOptionalMemoryFreeAdvanced": "LLaVA (Managed Cache, Advanced)",
|
||||
}
|
||||
|
||||
@@ -0,0 +1,162 @@
|
||||
"""MC-LLaVA node with in-memory images and ComfyUI-managed weights."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import torch
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
inference_context,
|
||||
model_device,
|
||||
move_inputs,
|
||||
require_module,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
MODEL_ID = "visheratin/MC-LLaVA-3b"
|
||||
|
||||
|
||||
class MCLLaVAModelPredictor:
|
||||
def __init__(self):
|
||||
transformers = require_module("transformers")
|
||||
model_path = snapshot_download(
|
||||
MODEL_ID, "mcllava", ignore_patterns=["*.bin"]
|
||||
)
|
||||
self.dtype = torch_dtype("float16")
|
||||
model = transformers.AutoModelForCausalLM.from_pretrained(
|
||||
model_path,
|
||||
torch_dtype=self.dtype,
|
||||
trust_remote_code=True,
|
||||
).eval()
|
||||
self.processor = transformers.AutoProcessor.from_pretrained(
|
||||
model_path, trust_remote_code=True
|
||||
)
|
||||
self.handle = ManagedTorchModel(model, processor=self.processor)
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
def generate(
|
||||
self,
|
||||
images,
|
||||
prompt,
|
||||
temperature,
|
||||
top_p,
|
||||
max_crops,
|
||||
num_tokens,
|
||||
max_new_tokens,
|
||||
):
|
||||
results = []
|
||||
formatted = (
|
||||
"<|im_start|>user\n<image>\n"
|
||||
f"{prompt}<|im_end|>\n<|im_start|>assistant\n"
|
||||
)
|
||||
for image in tensor_batch_to_pil(images):
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
inputs = self.processor(
|
||||
formatted,
|
||||
[image],
|
||||
model,
|
||||
max_crops=int(max_crops),
|
||||
num_tokens=int(num_tokens),
|
||||
)
|
||||
inputs = move_inputs(inputs, device)
|
||||
do_sample = float(temperature) > 0.0
|
||||
generation = {
|
||||
"max_new_tokens": int(max_new_tokens),
|
||||
"do_sample": do_sample,
|
||||
"use_cache": True,
|
||||
"eos_token_id": self.processor.tokenizer.eos_token_id,
|
||||
}
|
||||
if do_sample:
|
||||
generation.update(
|
||||
temperature=float(temperature), top_p=float(top_p)
|
||||
)
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
output = model.generate(**inputs, **generation)
|
||||
input_length = inputs["input_ids"].shape[-1]
|
||||
text = self.processor.tokenizer.decode(
|
||||
output[0, input_length:], skip_special_tokens=True
|
||||
)
|
||||
results.append(text.strip())
|
||||
return batch_text(results)
|
||||
|
||||
|
||||
class MCLLaVAModel(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"prompt": (
|
||||
"STRING",
|
||||
{"multiline": True, "default": "Describe the image."},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.1, "min": 0.0, "max": 2.0, "step": 0.01},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.9, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"max_crops": (
|
||||
"INT",
|
||||
{"default": 100, "min": 1, "max": 300, "step": 1},
|
||||
),
|
||||
"num_tokens": (
|
||||
"INT",
|
||||
{"default": 728, "min": 1, "max": 4096, "step": 1},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 200, "min": 1, "max": 4096},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "generate_image_description"
|
||||
CATEGORY = "VLM Nodes/Legacy/Model Loaders"
|
||||
|
||||
def generate_image_description(
|
||||
self,
|
||||
image,
|
||||
prompt,
|
||||
temperature,
|
||||
top_p,
|
||||
max_crops,
|
||||
num_tokens,
|
||||
max_new_tokens=200,
|
||||
unload_after=False,
|
||||
):
|
||||
predictor = self.get_or_create_model(
|
||||
MODEL_ID, MCLLaVAModelPredictor
|
||||
)
|
||||
try:
|
||||
return (
|
||||
predictor.generate(
|
||||
image,
|
||||
prompt,
|
||||
temperature,
|
||||
top_p,
|
||||
max_crops,
|
||||
num_tokens,
|
||||
max_new_tokens,
|
||||
),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"MCLLaVAModel": MCLLaVAModel}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"MCLLaVAModel": "MC-LLaVA"}
|
||||
@@ -0,0 +1,231 @@
|
||||
"""MiniCPM-V 2.6 GGUF node using llama.cpp's native vision handler."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
LlamaHandle,
|
||||
LlavaClipConfig,
|
||||
batch_text,
|
||||
default_llama_threads,
|
||||
hf_download,
|
||||
image_data_uri,
|
||||
llama_chat_content,
|
||||
llama_runtime_input_types,
|
||||
llama_runtime_options,
|
||||
tensor_batch_to_pil,
|
||||
)
|
||||
|
||||
MODEL_REPO = "openbmb/MiniCPM-V-2_6-gguf"
|
||||
GGUF_MODELS = {
|
||||
"Q2_K (3GB)": "ggml-model-Q2_K.gguf",
|
||||
"Q3_K (3.8GB)": "ggml-model-Q3_K.gguf",
|
||||
"Q4_K_M (4.7GB)": "ggml-model-Q4_K_M.gguf",
|
||||
"Q5_K_M (5.4GB)": "ggml-model-Q5_K_M.gguf",
|
||||
"Q8_0 (8.1GB)": "ggml-model-Q8_0.gguf",
|
||||
"F16 (15.2GB)": "ggml-model-f16.gguf",
|
||||
}
|
||||
|
||||
|
||||
class MiniCPMPredictor:
|
||||
def __init__(
|
||||
self,
|
||||
model_variant,
|
||||
context_length,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
runtime_options=None,
|
||||
):
|
||||
model_path = hf_download(
|
||||
MODEL_REPO,
|
||||
GGUF_MODELS[model_variant],
|
||||
"minicpm-v-2_6-gguf",
|
||||
)
|
||||
projector_path = hf_download(
|
||||
MODEL_REPO,
|
||||
"mmproj-model-f16.gguf",
|
||||
"minicpm-v-2_6-gguf",
|
||||
)
|
||||
|
||||
clip = LlavaClipConfig(projector_path, "MiniCPM-V 2.6")
|
||||
|
||||
def create_handler(*, use_gpu=True):
|
||||
return clip.create(use_gpu=use_gpu)
|
||||
|
||||
self.handle = LlamaHandle(
|
||||
model_path,
|
||||
n_ctx=int(context_length),
|
||||
n_gpu_layers=int(gpu_layers),
|
||||
n_threads=int(n_threads),
|
||||
chat_handler_factory=create_handler,
|
||||
projector_path=projector_path,
|
||||
**dict(runtime_options or {}),
|
||||
)
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
|
||||
def generate(
|
||||
self,
|
||||
images,
|
||||
prompt,
|
||||
temperature,
|
||||
top_p,
|
||||
top_k,
|
||||
repeat_penalty,
|
||||
max_tokens,
|
||||
):
|
||||
llm = self.handle.ensure_loaded()
|
||||
results = []
|
||||
for image in tensor_batch_to_pil(images):
|
||||
response = llm.create_chat_completion(
|
||||
messages=[
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "image_url",
|
||||
"image_url": {"url": image_data_uri(image)},
|
||||
},
|
||||
{"type": "text", "text": prompt},
|
||||
],
|
||||
}
|
||||
],
|
||||
max_tokens=int(max_tokens),
|
||||
temperature=float(temperature),
|
||||
top_p=float(top_p),
|
||||
top_k=int(top_k),
|
||||
repeat_penalty=float(repeat_penalty),
|
||||
)
|
||||
results.append(llama_chat_content(response))
|
||||
return batch_text(results)
|
||||
|
||||
|
||||
class MiniCPMNode(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"prompt": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "Describe this image in detail.",
|
||||
},
|
||||
),
|
||||
"model_variant": (list(GGUF_MODELS),),
|
||||
"context_length": (
|
||||
"INT",
|
||||
{"default": 4096, "min": 512, "max": 131072},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.2, "min": 0.0, "max": 2.0, "step": 0.1},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.8, "min": 0.0, "max": 1.0, "step": 0.05},
|
||||
),
|
||||
"top_k": (
|
||||
"INT",
|
||||
{"default": 100, "min": 0, "max": 1000},
|
||||
),
|
||||
"repeat_penalty": (
|
||||
"FLOAT",
|
||||
{"default": 1.05, "min": 0.0, "max": 2.0, "step": 0.05},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"gpu_layers": (
|
||||
"INT",
|
||||
{"default": -1, "min": -1, "max": 1000},
|
||||
),
|
||||
"n_threads": (
|
||||
"INT",
|
||||
{
|
||||
"default": default_llama_threads(),
|
||||
"min": 1,
|
||||
"max": 256,
|
||||
},
|
||||
),
|
||||
"max_tokens": (
|
||||
"INT",
|
||||
{"default": 512, "min": 1, "max": 8192},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
**llama_runtime_input_types(),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "generate"
|
||||
CATEGORY = "VLM Nodes/Legacy/Model Loaders"
|
||||
|
||||
def generate(
|
||||
self,
|
||||
image,
|
||||
prompt,
|
||||
model_variant,
|
||||
context_length=4096,
|
||||
temperature=0.2,
|
||||
top_p=0.8,
|
||||
top_k=100,
|
||||
repeat_penalty=1.05,
|
||||
gpu_layers=-1,
|
||||
n_threads=None,
|
||||
max_tokens=512,
|
||||
unload_after=False,
|
||||
n_batch=512,
|
||||
n_ubatch=512,
|
||||
flash_attention="Auto",
|
||||
use_mmap=True,
|
||||
split_mode="Layer",
|
||||
main_gpu=0,
|
||||
tensor_split="",
|
||||
):
|
||||
n_threads = default_llama_threads() if n_threads is None else int(n_threads)
|
||||
options = llama_runtime_options(
|
||||
n_batch=n_batch,
|
||||
n_ubatch=n_ubatch,
|
||||
flash_attention=flash_attention,
|
||||
use_mmap=use_mmap,
|
||||
split_mode=split_mode,
|
||||
main_gpu=main_gpu,
|
||||
tensor_split=tensor_split,
|
||||
)
|
||||
key = (
|
||||
model_variant,
|
||||
int(context_length),
|
||||
int(gpu_layers),
|
||||
int(n_threads),
|
||||
tuple(sorted(options.items())),
|
||||
)
|
||||
predictor = self.get_or_create_model(
|
||||
key,
|
||||
lambda: MiniCPMPredictor(
|
||||
model_variant,
|
||||
context_length,
|
||||
gpu_layers,
|
||||
n_threads,
|
||||
options,
|
||||
),
|
||||
)
|
||||
try:
|
||||
return (
|
||||
predictor.generate(
|
||||
image,
|
||||
prompt,
|
||||
temperature,
|
||||
top_p,
|
||||
top_k,
|
||||
repeat_penalty,
|
||||
max_tokens,
|
||||
),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"MiniCPMNode": MiniCPMNode}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"MiniCPMNode": "MiniCPM-V 2.6 (GGUF)"}
|
||||
@@ -0,0 +1,825 @@
|
||||
"""Modern, chat-template based vision-language models.
|
||||
|
||||
This node intentionally uses the Transformers multimodal auto classes instead
|
||||
of model-specific glue. It provides one stable ComfyUI surface for current
|
||||
small and large VLM families while keeping downloads and VRAM allocation lazy.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import threading
|
||||
from dataclasses import dataclass
|
||||
from typing import Any, Callable
|
||||
|
||||
import torch
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ExternalTorchModel,
|
||||
ManagedTorchModel,
|
||||
accelerator_backend,
|
||||
batch_text,
|
||||
execution_device,
|
||||
external_device_map,
|
||||
inference_context,
|
||||
model_device,
|
||||
move_inputs,
|
||||
normalize_hf_model_id,
|
||||
require_quantization_backend,
|
||||
require_module,
|
||||
reserve_external_vram,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
from .vision_types import VLM_VIDEO_SELECTION, VideoFrameSelection
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class ModelSpec:
|
||||
repo_id: str
|
||||
family: str
|
||||
estimated_gib: float
|
||||
gated: bool = False
|
||||
video: bool = False
|
||||
small_fast: bool = False
|
||||
trust_remote_code: bool = False
|
||||
|
||||
|
||||
# Deliberately curated: these are useful tiers, not every redundant checkpoint.
|
||||
MODEL_CATALOG = {
|
||||
"Qwen 3.5 0.8B (fastest current)": ModelSpec(
|
||||
"Qwen/Qwen3.5-0.8B",
|
||||
"Qwen 3.5",
|
||||
2.0,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Qwen 3.5 2B": ModelSpec(
|
||||
"Qwen/Qwen3.5-2B",
|
||||
"Qwen 3.5",
|
||||
4.5,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Qwen 3.5 4B (recommended)": ModelSpec(
|
||||
"Qwen/Qwen3.5-4B",
|
||||
"Qwen 3.5",
|
||||
8.5,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Qwen 3.5 9B": ModelSpec(
|
||||
"Qwen/Qwen3.5-9B", "Qwen 3.5", 19.0, video=True
|
||||
),
|
||||
"Qwen 3.5 27B (4-bit recommended)": ModelSpec(
|
||||
"Qwen/Qwen3.5-27B", "Qwen 3.5", 55.0, video=True
|
||||
),
|
||||
"Qwen 3.5 35B-A3B (4-bit recommended)": ModelSpec(
|
||||
"Qwen/Qwen3.5-35B-A3B", "Qwen 3.5", 72.0, video=True
|
||||
),
|
||||
"Qwen 3.6 27B (4-bit recommended)": ModelSpec(
|
||||
"Qwen/Qwen3.6-27B", "Qwen 3.6", 55.0, video=True
|
||||
),
|
||||
"Qwen 3 VL 2B Instruct": ModelSpec(
|
||||
"Qwen/Qwen3-VL-2B-Instruct",
|
||||
"Qwen 3 VL",
|
||||
5.0,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Qwen 3 VL 4B Instruct": ModelSpec(
|
||||
"Qwen/Qwen3-VL-4B-Instruct",
|
||||
"Qwen 3 VL",
|
||||
9.0,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Qwen 3 VL 8B Instruct": ModelSpec(
|
||||
"Qwen/Qwen3-VL-8B-Instruct", "Qwen 3 VL", 18.0, video=True
|
||||
),
|
||||
"Qwen 3 VL 30B-A3B Instruct (4-bit recommended)": ModelSpec(
|
||||
"Qwen/Qwen3-VL-30B-A3B-Instruct", "Qwen 3 VL", 61.0, video=True
|
||||
),
|
||||
"Qwen 2.5 VL 3B Instruct (legacy workflows)": ModelSpec(
|
||||
"Qwen/Qwen2.5-VL-3B-Instruct",
|
||||
"Qwen 2.5 VL",
|
||||
7.0,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Qwen 2.5 VL 7B Instruct (legacy workflows)": ModelSpec(
|
||||
"Qwen/Qwen2.5-VL-7B-Instruct", "Qwen 2.5 VL", 16.0, video=True
|
||||
),
|
||||
"Gemma 3 4B IT (license acceptance required)": ModelSpec(
|
||||
"google/gemma-3-4b-it",
|
||||
"Gemma 3",
|
||||
9.0,
|
||||
gated=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Gemma 3 12B IT (license acceptance required)": ModelSpec(
|
||||
"google/gemma-3-12b-it", "Gemma 3", 25.0, gated=True
|
||||
),
|
||||
"Gemma 3 27B IT (4-bit recommended, gated)": ModelSpec(
|
||||
"google/gemma-3-27b-it", "Gemma 3", 55.0, gated=True
|
||||
),
|
||||
"SmolVLM2 256M Video (smallest)": ModelSpec(
|
||||
"HuggingFaceTB/SmolVLM2-256M-Video-Instruct",
|
||||
"SmolVLM2",
|
||||
1.4,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"SmolVLM2 500M Video (low VRAM)": ModelSpec(
|
||||
"HuggingFaceTB/SmolVLM2-500M-Video-Instruct",
|
||||
"SmolVLM2",
|
||||
1.8,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"SmolVLM2 2.2B Video": ModelSpec(
|
||||
"HuggingFaceTB/SmolVLM2-2.2B-Instruct",
|
||||
"SmolVLM2",
|
||||
5.2,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"LFM2.5 VL 450M (edge)": ModelSpec(
|
||||
"LiquidAI/LFM2.5-VL-450M",
|
||||
"LFM2.5 VL",
|
||||
1.5,
|
||||
small_fast=True,
|
||||
),
|
||||
"LFM2.5 VL 1.6B": ModelSpec(
|
||||
"LiquidAI/LFM2.5-VL-1.6B",
|
||||
"LFM2.5 VL",
|
||||
4.0,
|
||||
small_fast=True,
|
||||
),
|
||||
"InternVL 3.5 1B HF": ModelSpec(
|
||||
"OpenGVLab/InternVL3_5-1B-HF",
|
||||
"InternVL 3.5",
|
||||
2.5,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"InternVL 3.5 2B HF": ModelSpec(
|
||||
"OpenGVLab/InternVL3_5-2B-HF",
|
||||
"InternVL 3.5",
|
||||
5.0,
|
||||
video=True,
|
||||
small_fast=True,
|
||||
),
|
||||
"Granite Vision 3.3 2B (documents/OCR)": ModelSpec(
|
||||
"ibm-granite/granite-vision-3.3-2b",
|
||||
"Granite Vision 3.3",
|
||||
6.5,
|
||||
small_fast=True,
|
||||
),
|
||||
"Granite Vision 4.1 4B (structured documents)": ModelSpec(
|
||||
"ibm-granite/granite-vision-4.1-4b",
|
||||
"Granite Vision 4.1",
|
||||
9.0,
|
||||
small_fast=True,
|
||||
),
|
||||
"Custom Hugging Face model": ModelSpec(
|
||||
"",
|
||||
"Custom",
|
||||
8.0,
|
||||
trust_remote_code=True,
|
||||
),
|
||||
}
|
||||
|
||||
RECOMMENDED_MODEL_LABELS = (
|
||||
"Qwen 3.5 0.8B (fastest current)",
|
||||
"Qwen 3.5 4B (recommended)",
|
||||
"Qwen 3 VL 2B Instruct",
|
||||
"Qwen 3 VL 4B Instruct",
|
||||
"Qwen 3 VL 8B Instruct",
|
||||
"SmolVLM2 500M Video (low VRAM)",
|
||||
"SmolVLM2 2.2B Video",
|
||||
"LFM2.5 VL 450M (edge)",
|
||||
"InternVL 3.5 1B HF",
|
||||
"Granite Vision 4.1 4B (structured documents)",
|
||||
"Gemma 3 4B IT (license acceptance required)",
|
||||
"Custom Hugging Face model",
|
||||
)
|
||||
LEGACY_MODEL_LABELS = tuple(
|
||||
label for label in MODEL_CATALOG if label not in RECOMMENDED_MODEL_LABELS
|
||||
)
|
||||
|
||||
MEMORY_MODES = (
|
||||
"ComfyUI managed (BF16)",
|
||||
"4-bit NF4 (bitsandbytes)",
|
||||
"8-bit (bitsandbytes)",
|
||||
"CPU",
|
||||
)
|
||||
ATTENTION_MODES = ("Auto (SDPA)", "Flash Attention 2", "Eager")
|
||||
|
||||
|
||||
def _progress_text_sender(node_id: str | None) -> Callable[[str], None] | None:
|
||||
"""Return a best-effort sender for ComfyUI's native progress-text channel."""
|
||||
|
||||
if node_id is None:
|
||||
return None
|
||||
try:
|
||||
from server import PromptServer
|
||||
|
||||
server = PromptServer.instance
|
||||
except (ImportError, AttributeError):
|
||||
return None
|
||||
|
||||
def send(text: str) -> None:
|
||||
try:
|
||||
server.send_progress_text(
|
||||
text,
|
||||
str(node_id),
|
||||
server.client_id,
|
||||
)
|
||||
except Exception:
|
||||
# Streaming is a UI enhancement and must never fail inference.
|
||||
return
|
||||
|
||||
return send
|
||||
|
||||
|
||||
def _model_class(transformers):
|
||||
for name in ("AutoModelForImageTextToText", "AutoModelForMultimodalLM"):
|
||||
model_class = getattr(transformers, name, None)
|
||||
if model_class is not None:
|
||||
return model_class
|
||||
raise RuntimeError(
|
||||
"Modern VLMs require a current Transformers release with "
|
||||
"AutoModelForImageTextToText support."
|
||||
)
|
||||
|
||||
|
||||
class ModernVLMPredictor:
|
||||
def __init__(
|
||||
self,
|
||||
model_label: str,
|
||||
custom_model_id: str,
|
||||
memory_mode: str,
|
||||
attention_mode: str,
|
||||
) -> None:
|
||||
transformers = require_module("transformers")
|
||||
self.streamer_class = getattr(transformers, "TextIteratorStreamer", None)
|
||||
spec = MODEL_CATALOG[model_label]
|
||||
repo_id = (
|
||||
normalize_hf_model_id(custom_model_id)
|
||||
if spec.family == "Custom"
|
||||
else spec.repo_id
|
||||
)
|
||||
self.spec = spec
|
||||
self.dtype = torch_dtype("bfloat16")
|
||||
if (
|
||||
attention_mode == "Flash Attention 2"
|
||||
and accelerator_backend(execution_device())
|
||||
not in {"nvidia-cuda", "amd-rocm"}
|
||||
):
|
||||
raise RuntimeError(
|
||||
"Flash Attention 2 requires a supported CUDA or ROCm build. "
|
||||
"Select Auto (SDPA) on Apple Metal, Intel XPU, or CPU."
|
||||
)
|
||||
quantization_device = None
|
||||
if memory_mode in {
|
||||
"4-bit NF4 (bitsandbytes)",
|
||||
"8-bit (bitsandbytes)",
|
||||
}:
|
||||
# Validate before downloading a multi-gigabyte checkpoint.
|
||||
quantization_device = require_quantization_backend(memory_mode)
|
||||
try:
|
||||
model_path = snapshot_download(
|
||||
repo_id,
|
||||
f"modern-vlm/{repo_id.replace('/', '--')}",
|
||||
ignore_patterns=["*.bin", "*.msgpack", "*.h5", "*.onnx"],
|
||||
)
|
||||
except Exception as exc:
|
||||
if spec.gated:
|
||||
raise RuntimeError(
|
||||
f"{repo_id} is gated. Accept its Hugging Face license and "
|
||||
"set HF_TOKEN before running this node."
|
||||
) from exc
|
||||
raise
|
||||
self.processor = transformers.AutoProcessor.from_pretrained(
|
||||
model_path,
|
||||
trust_remote_code=spec.trust_remote_code,
|
||||
)
|
||||
|
||||
attention = {
|
||||
# Let each architecture choose its maintained native kernel. Most
|
||||
# current PyTorch models select SDPA here, while hybrid edge models
|
||||
# can retain their own attention implementation.
|
||||
"Auto (SDPA)": None,
|
||||
"Flash Attention 2": "flash_attention_2",
|
||||
"Eager": "eager",
|
||||
}[attention_mode]
|
||||
kwargs: dict[str, Any] = {
|
||||
"dtype": self.dtype,
|
||||
"trust_remote_code": spec.trust_remote_code,
|
||||
}
|
||||
if attention is not None:
|
||||
kwargs["attn_implementation"] = attention
|
||||
external = memory_mode != "ComfyUI managed (BF16)"
|
||||
if memory_mode in {"4-bit NF4 (bitsandbytes)", "8-bit (bitsandbytes)"}:
|
||||
assert quantization_device is not None
|
||||
needs_offload = spec.estimated_gib >= 40.0
|
||||
kwargs["quantization_config"] = transformers.BitsAndBytesConfig(
|
||||
load_in_4bit=memory_mode.startswith("4-bit"),
|
||||
load_in_8bit=memory_mode.startswith("8-bit"),
|
||||
bnb_4bit_compute_dtype=self.dtype,
|
||||
bnb_4bit_quant_type="nf4",
|
||||
bnb_4bit_use_double_quant=True,
|
||||
llm_int8_enable_fp32_cpu_offload=needs_offload,
|
||||
)
|
||||
if needs_offload:
|
||||
# Automatic CPU/disk placement is maintained for CUDA, ROCm,
|
||||
# and XPU. MPS uses unified memory and CPU already runs in RAM,
|
||||
# so both stay on their explicit active device.
|
||||
kwargs["device_map"] = external_device_map(
|
||||
allow_auto_offload=True
|
||||
)
|
||||
kwargs["offload_folder"] = str(model_path / ".offload")
|
||||
else:
|
||||
# Avoid accidental dispatch to device zero when ComfyUI chose
|
||||
# another GPU, Apple Metal, Intel XPU, or CPU.
|
||||
kwargs["device_map"] = external_device_map()
|
||||
divisor = 4 if memory_mode.startswith("4-bit") else 2
|
||||
if quantization_device.type != "cpu":
|
||||
reserve_external_vram(
|
||||
int(spec.estimated_gib * 1024**3 / divisor)
|
||||
)
|
||||
elif memory_mode == "CPU":
|
||||
kwargs["dtype"] = torch.float32
|
||||
|
||||
try:
|
||||
model = _model_class(transformers).from_pretrained(
|
||||
model_path, **kwargs
|
||||
).eval()
|
||||
except OSError as exc:
|
||||
if spec.gated:
|
||||
raise RuntimeError(
|
||||
f"{repo_id} is gated. Accept its Hugging Face license and "
|
||||
"set HF_TOKEN before running this node."
|
||||
) from exc
|
||||
raise
|
||||
except ImportError as exc:
|
||||
if attention_mode == "Flash Attention 2":
|
||||
raise RuntimeError(
|
||||
"Flash Attention 2 is unavailable for this Python/PyTorch "
|
||||
"build. Select Auto (SDPA), or install a matching wheel."
|
||||
) from exc
|
||||
raise
|
||||
|
||||
self.handle = (
|
||||
ExternalTorchModel(model, processor=self.processor)
|
||||
if external
|
||||
else ManagedTorchModel(model, processor=self.processor)
|
||||
)
|
||||
|
||||
def close(self) -> None:
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
def _inputs(
|
||||
self,
|
||||
messages,
|
||||
enable_thinking: bool = False,
|
||||
*,
|
||||
video_metadata: dict[str, Any] | None = None,
|
||||
):
|
||||
"""Use the standard multimodal template, with an older-template fallback."""
|
||||
|
||||
template_kwargs = (
|
||||
{"enable_thinking": bool(enable_thinking)}
|
||||
if self.spec.family in {"Qwen 3.5", "Qwen 3.6"}
|
||||
else {}
|
||||
)
|
||||
processor_kwargs = (
|
||||
{
|
||||
"video_metadata": [[video_metadata]],
|
||||
# ComfyUI already supplied the selected frames as a batch.
|
||||
"do_sample_frames": False,
|
||||
}
|
||||
if video_metadata is not None
|
||||
else None
|
||||
)
|
||||
if processor_kwargs is not None and self.spec.family == "InternVL 3.5":
|
||||
# The published InternVL 3.5 video preprocessor uses 384px, which
|
||||
# makes a 27x27 patch grid with its 14px vision patches. The
|
||||
# model's 0.5 pixel shuffle requires even spatial dimensions.
|
||||
image_size = getattr(self.processor.image_processor, "size", None)
|
||||
processor_kwargs["size"] = (
|
||||
dict(image_size)
|
||||
if image_size is not None
|
||||
else {"height": 448, "width": 448}
|
||||
)
|
||||
try:
|
||||
return self.processor.apply_chat_template(
|
||||
messages,
|
||||
add_generation_prompt=True,
|
||||
tokenize=True,
|
||||
return_dict=True,
|
||||
return_tensors="pt",
|
||||
processor_kwargs=processor_kwargs,
|
||||
**template_kwargs,
|
||||
)
|
||||
except (TypeError, ValueError, KeyError):
|
||||
media = []
|
||||
portable_messages = []
|
||||
for message in messages:
|
||||
content = []
|
||||
for part in message["content"]:
|
||||
if part["type"] == "image":
|
||||
media.append(part["image"])
|
||||
content.append({"type": "image"})
|
||||
elif part["type"] == "video":
|
||||
media.extend(part["video"])
|
||||
content.extend({"type": "image"} for _ in part["video"])
|
||||
else:
|
||||
content.append(part)
|
||||
portable_messages.append(
|
||||
{"role": message["role"], "content": content}
|
||||
)
|
||||
prompt = self.processor.apply_chat_template(
|
||||
portable_messages,
|
||||
add_generation_prompt=True,
|
||||
tokenize=False,
|
||||
**template_kwargs,
|
||||
)
|
||||
return self.processor(
|
||||
text=[prompt], images=media, return_tensors="pt"
|
||||
)
|
||||
|
||||
def generate(
|
||||
self,
|
||||
images,
|
||||
prompt: str,
|
||||
system_prompt: str,
|
||||
max_new_tokens: int,
|
||||
temperature: float,
|
||||
top_p: float,
|
||||
video_frames=None,
|
||||
fps: float = 1.0,
|
||||
enable_thinking: bool = False,
|
||||
stream_callback: Callable[[str], None] | None = None,
|
||||
video_selection: VideoFrameSelection | None = None,
|
||||
) -> str:
|
||||
primary_images = (
|
||||
tensor_batch_to_pil(images) if images is not None else []
|
||||
)
|
||||
video = (
|
||||
tensor_batch_to_pil(video_frames)
|
||||
if video_frames is not None
|
||||
else None
|
||||
)
|
||||
if video is None and not primary_images:
|
||||
raise ValueError("Connect either image or video_frames.")
|
||||
if video is not None and not self.spec.video:
|
||||
raise ValueError(
|
||||
f"{self.spec.family} does not advertise video support. "
|
||||
"Disconnect video_frames or select Qwen/SmolVLM2."
|
||||
)
|
||||
if video_selection is not None:
|
||||
if video is None:
|
||||
raise ValueError(
|
||||
"video_selection requires a connected video_frames batch."
|
||||
)
|
||||
if not isinstance(video_selection, VideoFrameSelection):
|
||||
raise TypeError("video_selection must be a VLM Video Selection.")
|
||||
if len(video_selection.frames) != len(video):
|
||||
raise ValueError(
|
||||
"video_selection frame count must match video_frames."
|
||||
)
|
||||
source_aspect = video_selection.width / video_selection.height
|
||||
analysis_aspect = video[0].width / video[0].height
|
||||
if abs(source_aspect - analysis_aspect) > max(
|
||||
0.01,
|
||||
source_aspect * 0.01,
|
||||
):
|
||||
raise ValueError(
|
||||
"video_selection and video_frames must have the same "
|
||||
"aspect ratio."
|
||||
)
|
||||
|
||||
results = []
|
||||
# A connected video is the primary visual input. Including ComfyUI's
|
||||
# required still image as well makes small video models attend to the
|
||||
# still and silently ignore the frames.
|
||||
runs = [None] if video is not None else primary_images
|
||||
for image in runs:
|
||||
messages = []
|
||||
if system_prompt.strip():
|
||||
messages.append(
|
||||
{
|
||||
"role": "system",
|
||||
"content": [
|
||||
{"type": "text", "text": system_prompt.strip()}
|
||||
],
|
||||
}
|
||||
)
|
||||
content = (
|
||||
[{"type": "video", "video": video}]
|
||||
if video is not None
|
||||
else [{"type": "image", "image": image}]
|
||||
)
|
||||
if video is not None and video_selection is not None:
|
||||
timeline = ", ".join(
|
||||
f"{position}=frame {frame.source_frame_index} "
|
||||
f"at {frame.timestamp:.6f}s"
|
||||
for position, frame in enumerate(video_selection.frames)
|
||||
)
|
||||
effective_prompt = (
|
||||
"The supplied video images are irregular samples from one "
|
||||
f"{video_selection.source_frame_count}-frame video at "
|
||||
f"{video_selection.fps:g} FPS. Supplied-image mapping: "
|
||||
f"{timeline}.\n\n{prompt}"
|
||||
)
|
||||
elif video is not None:
|
||||
effective_prompt = (
|
||||
f"The video frames are sampled at {float(fps):g} FPS.\n\n"
|
||||
f"{prompt}"
|
||||
)
|
||||
else:
|
||||
effective_prompt = prompt
|
||||
content.append({"type": "text", "text": effective_prompt})
|
||||
messages.append({"role": "user", "content": content})
|
||||
|
||||
metadata = None
|
||||
if video is not None:
|
||||
if video_selection is not None:
|
||||
metadata = {
|
||||
"total_num_frames": video_selection.source_frame_count,
|
||||
"fps": video_selection.fps,
|
||||
"duration": video_selection.duration,
|
||||
"frames_indices": list(video_selection.indices),
|
||||
"width": video[0].width,
|
||||
"height": video[0].height,
|
||||
}
|
||||
else:
|
||||
frame_rate = float(fps)
|
||||
metadata = {
|
||||
"total_num_frames": len(video),
|
||||
"fps": frame_rate,
|
||||
"duration": len(video) / frame_rate,
|
||||
"frames_indices": list(range(len(video))),
|
||||
"width": video[0].width,
|
||||
"height": video[0].height,
|
||||
}
|
||||
inputs = self._inputs(
|
||||
messages,
|
||||
enable_thinking,
|
||||
video_metadata=metadata,
|
||||
)
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
inputs = move_inputs(inputs, device)
|
||||
input_length = inputs["input_ids"].shape[-1]
|
||||
generation: dict[str, Any] = {
|
||||
"max_new_tokens": int(max_new_tokens),
|
||||
"do_sample": float(temperature) > 0,
|
||||
}
|
||||
if generation["do_sample"]:
|
||||
generation.update(
|
||||
temperature=float(temperature), top_p=float(top_p)
|
||||
)
|
||||
streamer_class = self.streamer_class
|
||||
tokenizer = getattr(self.processor, "tokenizer", self.processor)
|
||||
if stream_callback is not None and streamer_class is not None:
|
||||
streamer = streamer_class(
|
||||
tokenizer,
|
||||
skip_prompt=True,
|
||||
skip_special_tokens=True,
|
||||
clean_up_tokenization_spaces=False,
|
||||
)
|
||||
generated = []
|
||||
errors: list[BaseException] = []
|
||||
|
||||
def generate_in_background() -> None:
|
||||
try:
|
||||
with (
|
||||
torch.inference_mode(),
|
||||
inference_context(device, self.dtype),
|
||||
):
|
||||
generated.append(
|
||||
model.generate(
|
||||
**inputs,
|
||||
**generation,
|
||||
streamer=streamer,
|
||||
)
|
||||
)
|
||||
except BaseException as exc:
|
||||
errors.append(exc)
|
||||
# Unblock TextIteratorStreamer if generation exits
|
||||
# before it can publish its normal stop signal.
|
||||
streamer.end()
|
||||
|
||||
worker = threading.Thread(
|
||||
target=generate_in_background,
|
||||
name="ComfyUI-VLM-token-stream",
|
||||
daemon=True,
|
||||
)
|
||||
worker.start()
|
||||
chunks = []
|
||||
for chunk in streamer:
|
||||
chunks.append(chunk)
|
||||
current = batch_text(
|
||||
[*results, "".join(chunks).strip()]
|
||||
)
|
||||
if current:
|
||||
stream_callback(current)
|
||||
worker.join()
|
||||
if errors:
|
||||
raise errors[0]
|
||||
|
||||
decoded = "".join(chunks).strip()
|
||||
if not decoded and generated:
|
||||
new_tokens = generated[0][:, input_length:]
|
||||
decoded = self.processor.batch_decode(
|
||||
new_tokens,
|
||||
skip_special_tokens=True,
|
||||
clean_up_tokenization_spaces=False,
|
||||
)[0].strip()
|
||||
results.append(decoded)
|
||||
else:
|
||||
with (
|
||||
torch.inference_mode(),
|
||||
inference_context(device, self.dtype),
|
||||
):
|
||||
output = model.generate(**inputs, **generation)
|
||||
new_tokens = output[:, input_length:]
|
||||
results.append(
|
||||
self.processor.batch_decode(
|
||||
new_tokens,
|
||||
skip_special_tokens=True,
|
||||
clean_up_tokenization_spaces=False,
|
||||
)[0].strip()
|
||||
)
|
||||
return batch_text(results)
|
||||
|
||||
|
||||
class ModernVLM(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"prompt": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "Describe this image precisely and in detail.",
|
||||
},
|
||||
),
|
||||
"model": (
|
||||
list(RECOMMENDED_MODEL_LABELS),
|
||||
{"default": "Qwen 3 VL 2B Instruct"},
|
||||
),
|
||||
"custom_model_id": ("STRING", {"default": ""}),
|
||||
"memory_mode": (
|
||||
MEMORY_MODES,
|
||||
{"default": "ComfyUI managed (BF16)"},
|
||||
),
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 512, "min": 1, "max": 16384},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.1, "min": 0.0, "max": 2.0, "step": 0.05},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.9, "min": 0.01, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"image": ("IMAGE",),
|
||||
"system_prompt": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "You are an expert visual analyst.",
|
||||
},
|
||||
),
|
||||
"video_frames": ("IMAGE",),
|
||||
"video_selection": (VLM_VIDEO_SELECTION,),
|
||||
"fps": (
|
||||
"FLOAT",
|
||||
{"default": 1.0, "min": 0.1, "max": 60.0, "step": 0.1},
|
||||
),
|
||||
"attention_mode": (
|
||||
ATTENTION_MODES,
|
||||
{"default": "Auto (SDPA)"},
|
||||
),
|
||||
"enable_thinking": ("BOOLEAN", {"default": False}),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
"stream_output": (
|
||||
"BOOLEAN",
|
||||
{
|
||||
"default": True,
|
||||
"tooltip": (
|
||||
"Stream generated text through ComfyUI's native "
|
||||
"progress-text WebSocket while inference runs."
|
||||
),
|
||||
},
|
||||
),
|
||||
},
|
||||
"hidden": {"unique_id": "UNIQUE_ID"},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "run"
|
||||
CATEGORY = "VLM Nodes/Modern"
|
||||
|
||||
@classmethod
|
||||
def VALIDATE_INPUTS(cls, model):
|
||||
# The visible combo is deliberately curated. Accepting every known
|
||||
# catalog value here keeps workflows saved before the curation fully
|
||||
# executable even when their model now lives under Legacy.
|
||||
if model not in MODEL_CATALOG:
|
||||
return f"Unsupported Modern VLM model {model!r}."
|
||||
return True
|
||||
|
||||
def run(
|
||||
self,
|
||||
prompt,
|
||||
model,
|
||||
custom_model_id,
|
||||
memory_mode,
|
||||
max_new_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
image=None,
|
||||
system_prompt="You are an expert visual analyst.",
|
||||
video_frames=None,
|
||||
video_selection=None,
|
||||
fps=1.0,
|
||||
attention_mode="Auto (SDPA)",
|
||||
enable_thinking=False,
|
||||
unload_after=False,
|
||||
stream_output=True,
|
||||
unique_id=None,
|
||||
):
|
||||
stream_callback = (
|
||||
_progress_text_sender(unique_id) if stream_output else None
|
||||
)
|
||||
if stream_callback is not None:
|
||||
stream_callback("Preparing model…")
|
||||
effective_custom_id = (
|
||||
normalize_hf_model_id(custom_model_id)
|
||||
if model == "Custom Hugging Face model"
|
||||
else ""
|
||||
)
|
||||
key = (model, effective_custom_id, memory_mode, attention_mode)
|
||||
predictor = self.get_or_create_model(
|
||||
key,
|
||||
lambda: ModernVLMPredictor(
|
||||
model, effective_custom_id, memory_mode, attention_mode
|
||||
),
|
||||
)
|
||||
try:
|
||||
return (
|
||||
predictor.generate(
|
||||
images=image,
|
||||
prompt=prompt,
|
||||
system_prompt=system_prompt,
|
||||
max_new_tokens=max_new_tokens,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
video_frames=video_frames,
|
||||
fps=fps,
|
||||
video_selection=video_selection,
|
||||
enable_thinking=enable_thinking,
|
||||
stream_callback=stream_callback,
|
||||
),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
class LegacyModernVLM(ModernVLM):
|
||||
"""Compatibility surface for redundant, superseded, and very large tiers."""
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
inputs = super().INPUT_TYPES()
|
||||
inputs["required"]["model"] = (
|
||||
list(LEGACY_MODEL_LABELS),
|
||||
{"default": LEGACY_MODEL_LABELS[0]},
|
||||
)
|
||||
return inputs
|
||||
|
||||
CATEGORY = "VLM Nodes/Legacy/Model Loaders"
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"ModernVLM": ModernVLM,
|
||||
"LegacyModernVLM": LegacyModernVLM,
|
||||
}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"ModernVLM": (
|
||||
"Modern VLM (Qwen / SmolVLM2 / LFM / InternVL / Granite / Gemma)"
|
||||
),
|
||||
"LegacyModernVLM": "[Legacy] Modern VLM Compatibility",
|
||||
}
|
||||
+196
@@ -0,0 +1,196 @@
|
||||
"""AllenAI Molmo nodes with batch support and deterministic model ownership."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ExternalTorchModel,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
external_device_map,
|
||||
inference_context,
|
||||
model_device,
|
||||
require_quantization_backend,
|
||||
require_module,
|
||||
reserve_external_vram,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
MEMORY_MODES = {
|
||||
"Full Precision (45GB+ Required)": "managed",
|
||||
"8-bit Quantized (25GB+ Required)": "8bit",
|
||||
"4-bit Quantized (15GB+ Required)": "4bit",
|
||||
"4-bit + CPU Offload (12GB+ Required)": "4bit-offload",
|
||||
}
|
||||
MOLMO_MODELS = {
|
||||
"MolmoE-1B (Efficient)": "allenai/MolmoE-1B-0924",
|
||||
"Molmo-7B-D (Best 7B)": "allenai/Molmo-7B-D-0924",
|
||||
"Molmo-7B-O (Alternative 7B)": "allenai/Molmo-7B-O-0924",
|
||||
}
|
||||
|
||||
|
||||
class MolmoPredictor:
|
||||
def __init__(self, model_name, memory_mode, use_autocast):
|
||||
transformers = require_module("transformers")
|
||||
repo_id = MOLMO_MODELS[model_name]
|
||||
mode = MEMORY_MODES[memory_mode]
|
||||
external = mode != "managed"
|
||||
if external:
|
||||
# Validate before downloading a multi-gigabyte checkpoint.
|
||||
require_quantization_backend(memory_mode)
|
||||
path = snapshot_download(
|
||||
repo_id,
|
||||
f"molmo/{repo_id.replace('/', '--')}",
|
||||
ignore_patterns=["*.bin"],
|
||||
)
|
||||
self.dtype = torch_dtype("bfloat16")
|
||||
self.use_autocast = bool(use_autocast)
|
||||
self.processor = transformers.AutoProcessor.from_pretrained(
|
||||
path, trust_remote_code=True
|
||||
)
|
||||
kwargs: dict[str, Any] = {
|
||||
"trust_remote_code": True,
|
||||
"dtype": self.dtype,
|
||||
}
|
||||
if external:
|
||||
kwargs["quantization_config"] = transformers.BitsAndBytesConfig(
|
||||
load_in_8bit=mode == "8bit",
|
||||
load_in_4bit=mode.startswith("4bit"),
|
||||
bnb_4bit_compute_dtype=self.dtype,
|
||||
bnb_4bit_quant_type="nf4",
|
||||
bnb_4bit_use_double_quant=True,
|
||||
)
|
||||
kwargs["device_map"] = external_device_map(
|
||||
allow_auto_offload=mode == "4bit-offload"
|
||||
)
|
||||
reserve_external_vram(
|
||||
(5 if "1B" in model_name else 12) * 1024**3
|
||||
)
|
||||
model = transformers.AutoModelForCausalLM.from_pretrained(
|
||||
path, **kwargs
|
||||
).eval()
|
||||
self.handle = (
|
||||
ExternalTorchModel(model, processor=self.processor)
|
||||
if external
|
||||
else ManagedTorchModel(model, processor=self.processor)
|
||||
)
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
def generate(self, image, prompt, max_new_tokens, temperature, top_p, top_k):
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
inputs = self.processor.process(images=[image], text=prompt)
|
||||
inputs = {
|
||||
key: value.to(device).unsqueeze(0)
|
||||
for key, value in inputs.items()
|
||||
}
|
||||
config = require_module("transformers").GenerationConfig(
|
||||
max_new_tokens=int(max_new_tokens),
|
||||
do_sample=float(temperature) > 0,
|
||||
temperature=max(float(temperature), 1e-5),
|
||||
top_p=float(top_p),
|
||||
top_k=int(top_k),
|
||||
stop_strings="<|endoftext|>",
|
||||
pad_token_id=self.processor.tokenizer.pad_token_id,
|
||||
eos_token_id=self.processor.tokenizer.eos_token_id,
|
||||
)
|
||||
context = (
|
||||
inference_context(device, self.dtype)
|
||||
if self.use_autocast
|
||||
else torch.no_grad()
|
||||
)
|
||||
with torch.inference_mode(), context:
|
||||
output = model.generate_from_batch(
|
||||
inputs, config, tokenizer=self.processor.tokenizer
|
||||
)
|
||||
return self.processor.tokenizer.decode(
|
||||
output[0, inputs["input_ids"].shape[1]:],
|
||||
skip_special_tokens=True,
|
||||
).strip()
|
||||
|
||||
|
||||
class MolmoNode(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"prompt": (
|
||||
"STRING",
|
||||
{"multiline": True, "default": "Describe this image in detail."},
|
||||
),
|
||||
"model_name": (list(MOLMO_MODELS),),
|
||||
"memory_mode": (
|
||||
list(MEMORY_MODES),
|
||||
{"default": "4-bit Quantized (15GB+ Required)"},
|
||||
),
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 200, "min": 1, "max": 2048},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.2, "min": 0.0, "max": 2.0, "step": 0.1},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.9, "min": 0.01, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"top_k": ("INT", {"default": 50, "min": 1, "max": 100}),
|
||||
"use_autocast": ("BOOLEAN", {"default": True}),
|
||||
},
|
||||
"optional": {
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "generate"
|
||||
CATEGORY = "VLM Nodes/Legacy/Model Loaders"
|
||||
|
||||
def generate(
|
||||
self,
|
||||
image,
|
||||
prompt,
|
||||
model_name,
|
||||
memory_mode="4-bit Quantized (15GB+ Required)",
|
||||
max_new_tokens=200,
|
||||
temperature=0.2,
|
||||
top_p=0.9,
|
||||
top_k=50,
|
||||
use_autocast=True,
|
||||
unload_after=False,
|
||||
):
|
||||
predictor = self.get_or_create_model(
|
||||
(model_name, memory_mode, bool(use_autocast)),
|
||||
lambda: MolmoPredictor(model_name, memory_mode, use_autocast),
|
||||
)
|
||||
try:
|
||||
return (
|
||||
batch_text(
|
||||
predictor.generate(
|
||||
pil,
|
||||
prompt,
|
||||
max_new_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
top_k,
|
||||
)
|
||||
for pil in tensor_batch_to_pil(image)
|
||||
),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"MolmoNode": MolmoNode}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"MolmoNode": "Molmo Vision-Language Model"}
|
||||
@@ -1,2 +0,0 @@
|
||||
from .vision_encoder import VisionEncoder
|
||||
from .text_model import TextModel
|
||||
@@ -1,66 +0,0 @@
|
||||
# Copyright (c) Microsoft Corporation.
|
||||
# Licensed under the MIT license.
|
||||
|
||||
import math
|
||||
from typing import Optional
|
||||
|
||||
from transformers import PretrainedConfig
|
||||
|
||||
|
||||
class PhiConfig(PretrainedConfig):
|
||||
"""Phi configuration."""
|
||||
|
||||
model_type = "phi-msft"
|
||||
attribute_map = {
|
||||
"max_position_embeddings": "n_positions",
|
||||
"hidden_size": "n_embd",
|
||||
"num_attention_heads": "n_head",
|
||||
"num_hidden_layers": "n_layer",
|
||||
}
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
vocab_size: int = 50304,
|
||||
n_positions: int = 2048,
|
||||
n_embd: int = 1024,
|
||||
n_layer: int = 20,
|
||||
n_inner: Optional[int] = None,
|
||||
n_head: int = 16,
|
||||
n_head_kv: Optional[int] = None,
|
||||
rotary_dim: Optional[int] = 32,
|
||||
activation_function: Optional[str] = "gelu_new",
|
||||
flash_attn: bool = False,
|
||||
flash_rotary: bool = False,
|
||||
fused_dense: bool = False,
|
||||
attn_pdrop: float = 0.0,
|
||||
embd_pdrop: float = 0.0,
|
||||
resid_pdrop: float = 0.0,
|
||||
layer_norm_epsilon: float = 1e-5,
|
||||
initializer_range: float = 0.02,
|
||||
tie_word_embeddings: bool = False,
|
||||
pad_vocab_size_multiple: int = 64,
|
||||
gradient_checkpointing: bool = False,
|
||||
**kwargs
|
||||
) -> None:
|
||||
self.vocab_size = int(
|
||||
math.ceil(vocab_size / pad_vocab_size_multiple) * pad_vocab_size_multiple
|
||||
)
|
||||
self.n_positions = n_positions
|
||||
self.n_embd = n_embd
|
||||
self.n_layer = n_layer
|
||||
self.n_inner = n_inner
|
||||
self.n_head = n_head
|
||||
self.n_head_kv = n_head_kv
|
||||
self.rotary_dim = min(rotary_dim, n_embd // n_head)
|
||||
self.activation_function = activation_function
|
||||
self.flash_attn = flash_attn
|
||||
self.flash_rotary = flash_rotary
|
||||
self.fused_dense = fused_dense
|
||||
self.attn_pdrop = attn_pdrop
|
||||
self.embd_pdrop = embd_pdrop
|
||||
self.resid_pdrop = resid_pdrop
|
||||
self.layer_norm_epsilon = layer_norm_epsilon
|
||||
self.initializer_range = initializer_range
|
||||
self.gradient_checkpointing = gradient_checkpointing
|
||||
|
||||
super().__init__(tie_word_embeddings=tie_word_embeddings, **kwargs)
|
||||
File diff suppressed because it is too large
Load Diff
@@ -1,86 +0,0 @@
|
||||
import torch
|
||||
import transformers
|
||||
from transformers import CodeGenTokenizerFast as Tokenizer
|
||||
from accelerate import init_empty_weights, load_checkpoint_and_dispatch
|
||||
from .phi.configuration_phi import PhiConfig
|
||||
from .phi.modeling_phi import PhiForCausalLM
|
||||
import re
|
||||
|
||||
transformers.logging.set_verbosity_error()
|
||||
|
||||
|
||||
class TextModel:
|
||||
def __init__(self, model_path: str = "model") -> None:
|
||||
super().__init__()
|
||||
self.tokenizer = Tokenizer.from_pretrained(f"{model_path}/tokenizer")
|
||||
phi_config = PhiConfig.from_pretrained(f"{model_path}/text_model_cfg.json")
|
||||
|
||||
with init_empty_weights():
|
||||
self.model = PhiForCausalLM(phi_config)
|
||||
|
||||
self.model = load_checkpoint_and_dispatch(
|
||||
self.model,
|
||||
f"{model_path}/text_model.pt",
|
||||
device_map="auto",
|
||||
)
|
||||
|
||||
self.text_emb = self.model.get_input_embeddings()
|
||||
|
||||
def input_embeds(self, prompt, image_embeds):
|
||||
embeds = []
|
||||
|
||||
def _add_toks(toks):
|
||||
embeds.append(self.text_emb(toks))
|
||||
|
||||
def _tokenize(txt):
|
||||
return self.tokenizer(
|
||||
txt, return_tensors="pt", add_special_tokens=False
|
||||
).input_ids.to(self.model.device)
|
||||
|
||||
# Add BOS token
|
||||
_add_toks(
|
||||
torch.tensor([[self.tokenizer.bos_token_id]], device=self.model.device)
|
||||
)
|
||||
|
||||
if "<image>" not in prompt:
|
||||
embeds.append(self.text_emb(_tokenize(prompt)))
|
||||
else:
|
||||
assert prompt.count("<image>") == 1
|
||||
before, after = prompt.split("<image>")
|
||||
embeds.append(self.text_emb(_tokenize(f"{before}<image>")))
|
||||
embeds.append(image_embeds.to(self.model.device))
|
||||
embeds.append(self.text_emb(_tokenize(f"</image>{after}")))
|
||||
|
||||
return torch.cat(embeds, dim=1)
|
||||
|
||||
def generate(
|
||||
self, image_embeds, prompt, eos_text="Human:", max_new_tokens=128, **kwargs
|
||||
):
|
||||
eos_tokens = self.tokenizer(eos_text, add_special_tokens=False)[0].ids
|
||||
|
||||
generate_config = {
|
||||
"eos_token_id": eos_tokens,
|
||||
"bos_token_id": self.tokenizer.bos_token_id,
|
||||
"pad_token_id": self.tokenizer.eos_token_id,
|
||||
"max_new_tokens": max_new_tokens,
|
||||
**kwargs,
|
||||
}
|
||||
|
||||
with torch.no_grad():
|
||||
inputs_embeds = self.input_embeds(prompt, image_embeds)
|
||||
output_ids = self.model.generate(
|
||||
inputs_embeds=inputs_embeds, **generate_config
|
||||
)
|
||||
|
||||
return self.tokenizer.batch_decode(output_ids, skip_special_tokens=True)
|
||||
|
||||
def answer_question(self, image_embeds, question):
|
||||
prompt = f"<image>\n\nQuestion: {question}\n\nAnswer:"
|
||||
answer = self.generate(
|
||||
image_embeds,
|
||||
prompt,
|
||||
eos_text="<END>",
|
||||
max_new_tokens=128,
|
||||
)[0]
|
||||
|
||||
return re.sub("<$", "", re.sub("END$", "", answer)).strip()
|
||||
@@ -1,35 +0,0 @@
|
||||
import torch
|
||||
from PIL import Image
|
||||
from einops import rearrange
|
||||
from torchvision.transforms.v2 import (
|
||||
Compose,
|
||||
Resize,
|
||||
InterpolationMode,
|
||||
ToImage,
|
||||
ToDtype,
|
||||
Normalize,
|
||||
)
|
||||
|
||||
|
||||
|
||||
class VisionEncoder:
|
||||
def __init__(self, model_path: str = "model") -> None:
|
||||
self.model = torch.jit.load(f"{model_path}/vision.pt").to(dtype=torch.float32)
|
||||
self.preprocess = Compose(
|
||||
[
|
||||
Resize(size=(384, 384), interpolation=InterpolationMode.BICUBIC),
|
||||
ToImage(),
|
||||
ToDtype(torch.float32, scale=True),
|
||||
Normalize(mean=[0.5, 0.5, 0.5], std=[0.5, 0.5, 0.5]),
|
||||
]
|
||||
)
|
||||
|
||||
def __call__(self, image: Image) -> torch.Tensor:
|
||||
with torch.no_grad():
|
||||
image_vec = self.preprocess(image.convert("RGB")).unsqueeze(0)
|
||||
image_vec = image_vec[:, :, :-6, :-6]
|
||||
image_vec = rearrange(
|
||||
image_vec, "b c (h p1) (w p2) -> b (h w) (c p1 p2)", p1=14, p2=14
|
||||
)
|
||||
|
||||
return self.model(image_vec)
|
||||
@@ -0,0 +1,205 @@
|
||||
"""Current Moondream 2 node using the model's supported query API.
|
||||
|
||||
The pinned checkpoint was authored against Transformers 4.52.4. Loading it
|
||||
through Transformers 5's ``from_pretrained`` compatibility path can silently
|
||||
produce an all-EOS model even when every tensor is reported as loaded. The
|
||||
checkpoint itself is a normal safetensors state dict, so instantiate its
|
||||
official wrapper and load that state dict directly. This keeps Moondream in
|
||||
ComfyUI's managed VRAM lifecycle without downgrading Transformers for the rest
|
||||
of the node pack.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import importlib
|
||||
import sys
|
||||
from pathlib import Path
|
||||
from types import ModuleType
|
||||
|
||||
import torch
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
inference_context,
|
||||
model_device,
|
||||
require_module,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
MODEL_ID = "vikhyatk/moondream2"
|
||||
MODEL_REVISION = "2025-06-21"
|
||||
_CHECKPOINT_PACKAGE = "_comfyui_vlm_moondream2_checkpoint"
|
||||
|
||||
|
||||
def _checkpoint_module(model_path: str | Path):
|
||||
"""Import the checkpoint's relative modules without HF's generated cache.
|
||||
|
||||
Hugging Face's dynamic-module cache can omit transitive relative imports
|
||||
for a local snapshot. Giving the snapshot a private package namespace lets
|
||||
Python resolve the checkpoint's own ``.config``, ``.vision``, and related
|
||||
modules directly and deterministically.
|
||||
"""
|
||||
|
||||
source = str(Path(model_path).resolve())
|
||||
package = sys.modules.get(_CHECKPOINT_PACKAGE)
|
||||
if package is None:
|
||||
package = ModuleType(_CHECKPOINT_PACKAGE)
|
||||
package.__path__ = [source]
|
||||
package.__package__ = _CHECKPOINT_PACKAGE
|
||||
sys.modules[_CHECKPOINT_PACKAGE] = package
|
||||
elif list(getattr(package, "__path__", ())) != [source]:
|
||||
raise RuntimeError(
|
||||
"Moondream2 checkpoint source changed inside a running process. "
|
||||
"Restart ComfyUI before loading a different snapshot."
|
||||
)
|
||||
return importlib.import_module(f"{_CHECKPOINT_PACKAGE}.hf_moondream")
|
||||
|
||||
|
||||
def _load_native_checkpoint(model_path: str | Path):
|
||||
checkpoint = _checkpoint_module(model_path)
|
||||
safetensors = require_module("safetensors.torch")
|
||||
config = checkpoint.HfConfig.from_pretrained(
|
||||
model_path,
|
||||
local_files_only=True,
|
||||
)
|
||||
model = checkpoint.HfMoondream(config)
|
||||
weights = Path(model_path) / "model.safetensors"
|
||||
if not weights.is_file():
|
||||
raise FileNotFoundError(f"Moondream2 weights are missing: {weights}")
|
||||
missing, unexpected = safetensors.load_model(
|
||||
model,
|
||||
str(weights),
|
||||
strict=True,
|
||||
)
|
||||
if missing or unexpected:
|
||||
raise RuntimeError(
|
||||
"Moondream2 checkpoint did not load exactly: "
|
||||
f"missing={sorted(missing)}, unexpected={sorted(unexpected)}"
|
||||
)
|
||||
return model.eval()
|
||||
|
||||
|
||||
class Moondream2Predictor:
|
||||
def __init__(self):
|
||||
model_path = snapshot_download(
|
||||
MODEL_ID,
|
||||
"moondream2",
|
||||
revision=MODEL_REVISION,
|
||||
ignore_patterns=["*.bin", "*.gguf"],
|
||||
)
|
||||
self.dtype = torch_dtype("bfloat16")
|
||||
model = _load_native_checkpoint(model_path)
|
||||
self.handle = ManagedTorchModel(model)
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
|
||||
def generate(
|
||||
self,
|
||||
images,
|
||||
question,
|
||||
max_tokens=256,
|
||||
temperature=0.0,
|
||||
top_p=0.3,
|
||||
reasoning=False,
|
||||
):
|
||||
results = []
|
||||
for image in tensor_batch_to_pil(images):
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
response = model.query(
|
||||
image,
|
||||
question,
|
||||
reasoning=bool(reasoning),
|
||||
settings={
|
||||
"max_tokens": int(max_tokens),
|
||||
"temperature": float(temperature),
|
||||
"top_p": float(top_p),
|
||||
# Moondream's encoder indexes this optional key
|
||||
# directly; None selects the base checkpoint.
|
||||
"variant": None,
|
||||
},
|
||||
)
|
||||
if isinstance(response, dict):
|
||||
response = response.get("answer", response)
|
||||
if not str(response).strip():
|
||||
raise RuntimeError(
|
||||
"Moondream2 returned an empty response. Verify that the "
|
||||
f"{MODEL_REVISION} snapshot is complete, then restart "
|
||||
"ComfyUI so its checkpoint modules are reloaded."
|
||||
)
|
||||
results.append(str(response))
|
||||
return batch_text(results)
|
||||
|
||||
|
||||
class Moondream2model(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"text_input": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "Describe this image in detail.",
|
||||
},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"max_tokens": (
|
||||
"INT",
|
||||
{"default": 256, "min": 1, "max": 2048},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.0, "min": 0.0, "max": 2.0, "step": 0.05},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.3, "min": 0.01, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"reasoning": ("BOOLEAN", {"default": False}),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "moondream2_generate_predictions"
|
||||
CATEGORY = "VLM Nodes/Modern/Edge"
|
||||
|
||||
def moondream2_generate_predictions(
|
||||
self,
|
||||
image,
|
||||
text_input,
|
||||
max_tokens=256,
|
||||
temperature=0.0,
|
||||
top_p=0.3,
|
||||
reasoning=False,
|
||||
unload_after=False,
|
||||
):
|
||||
predictor = self.get_or_create_model(
|
||||
(MODEL_ID, MODEL_REVISION), Moondream2Predictor
|
||||
)
|
||||
try:
|
||||
return (
|
||||
predictor.generate(
|
||||
image,
|
||||
text_input,
|
||||
max_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
reasoning,
|
||||
),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"Moondream2model": Moondream2model}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Moondream2model": "Moondream 2"}
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,388 @@
|
||||
"""Isolated Moondream 3.1 Photon worker.
|
||||
|
||||
This file is launched directly by the ComfyUI process with the dedicated
|
||||
Moondream virtual environment. It intentionally has no imports from ComfyUI
|
||||
or this package: Moondream pins a Pillow version that is incompatible with
|
||||
current ComfyUI releases, so sharing one Python environment is unsafe.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import os
|
||||
import platform
|
||||
import sys
|
||||
import time
|
||||
import traceback
|
||||
from collections.abc import Callable
|
||||
from concurrent.futures import ThreadPoolExecutor
|
||||
from dataclasses import replace
|
||||
from importlib.metadata import PackageNotFoundError, version
|
||||
from io import BytesIO
|
||||
from multiprocessing.connection import Client
|
||||
from typing import Any
|
||||
|
||||
from PIL import Image
|
||||
|
||||
|
||||
def _honor_do_not_track() -> bool:
|
||||
"""Disable anonymous Photon reporting when the sidecar requests privacy.
|
||||
|
||||
Kestrel 0.4.2 does not currently inspect the conventional DO_NOT_TRACK
|
||||
environment variable. Base-model inference does not need its reporter, so
|
||||
keep validation local, skip the telemetry loop, and still close the HTTP
|
||||
client during engine shutdown. Finetune inference retains upstream auth
|
||||
and reporting behavior because it explicitly receives an API key.
|
||||
"""
|
||||
|
||||
if os.environ.get("DO_NOT_TRACK") != "1":
|
||||
return False
|
||||
if os.environ.get("MOONDREAM_API_KEY", "").strip():
|
||||
return False
|
||||
|
||||
from kestrel.photon import PhotonReporter
|
||||
|
||||
async def validate_api_key(self) -> bool:
|
||||
return False
|
||||
|
||||
def start(self) -> None:
|
||||
return None
|
||||
|
||||
async def shutdown(self) -> None:
|
||||
await self._client.aclose()
|
||||
|
||||
PhotonReporter.validate_api_key = validate_api_key
|
||||
PhotonReporter.start = start
|
||||
PhotonReporter.shutdown = shutdown
|
||||
return True
|
||||
|
||||
|
||||
def _register_moondream31_if_needed(model_name: str) -> bool:
|
||||
"""Bridge the official model-card ID on runtimes released before the ID.
|
||||
|
||||
Moondream 3.1 uses the same MD3 Photon runtime/checkpoint format as the
|
||||
preview. Stable moondream 1.3.0 / kestrel 0.4.2 shipped the safetensors
|
||||
loader but omitted the new registry entry published by the later model
|
||||
card. Prefer an upstream entry whenever present; otherwise clone only the
|
||||
runtime metadata and point it at the official 3.1 weights.
|
||||
"""
|
||||
|
||||
if model_name != "moondream3.1-9B-A2B":
|
||||
return False
|
||||
from kestrel.models import get_spec, register
|
||||
|
||||
try:
|
||||
get_spec(model_name)
|
||||
return False
|
||||
except ValueError:
|
||||
preview = get_spec("moondream3-preview")
|
||||
register(
|
||||
replace(
|
||||
preview,
|
||||
name=model_name,
|
||||
repo_id="moondream/moondream3.1-9B-A2B",
|
||||
filename="model.safetensors",
|
||||
checkpoint_format="md3",
|
||||
)
|
||||
)
|
||||
return True
|
||||
|
||||
|
||||
def _base_model_name(value: str) -> str:
|
||||
return str(value).split("/", 1)[0]
|
||||
|
||||
|
||||
def _model_skills(model_name: str) -> frozenset[str]:
|
||||
base_model = _base_model_name(model_name)
|
||||
if base_model == "moondream3.1-9B-A2B":
|
||||
# Source of truth: the final 3.1 model card. Segment remains a skill
|
||||
# of the 3 Preview and cloud API, not the final local 3.1 checkpoint.
|
||||
return frozenset(("caption", "query", "detect", "point"))
|
||||
from kestrel.models import get_spec
|
||||
|
||||
spec = get_spec(base_model)
|
||||
templates = spec.default_config.get("tokenizer", {}).get("templates", {})
|
||||
return frozenset(
|
||||
name for name, template in templates.items() if template is not None
|
||||
)
|
||||
|
||||
|
||||
def _image(value: bytes) -> Image.Image:
|
||||
if not isinstance(value, bytes):
|
||||
raise TypeError("Worker image payloads must be bytes.")
|
||||
with Image.open(BytesIO(value)) as source:
|
||||
return source.convert("RGB")
|
||||
|
||||
|
||||
def _parallel(
|
||||
images: list[bytes],
|
||||
operation: Callable[[Image.Image], dict[str, Any]],
|
||||
workers: int,
|
||||
) -> list[dict[str, Any]]:
|
||||
if not images:
|
||||
return []
|
||||
worker_count = max(1, min(int(workers), len(images)))
|
||||
with ThreadPoolExecutor(max_workers=worker_count) as pool:
|
||||
return list(pool.map(lambda value: operation(_image(value)), images))
|
||||
|
||||
|
||||
def _private_shutdown(model: Any) -> None:
|
||||
"""Best-effort graceful Photon shutdown before the process exits.
|
||||
|
||||
The public moondream package currently has no close method. Process
|
||||
isolation remains the hard guarantee: the parent terminates this exact
|
||||
process if this best-effort private cleanup ever changes or stalls.
|
||||
"""
|
||||
|
||||
engine = getattr(model, "_engine", None)
|
||||
loop = getattr(model, "_loop", None)
|
||||
thread = getattr(model, "_thread", None)
|
||||
if engine is not None and loop is not None:
|
||||
try:
|
||||
import asyncio
|
||||
|
||||
asyncio.run_coroutine_threadsafe(engine.shutdown(), loop).result(timeout=20)
|
||||
except Exception: # noqa: BLE001,S110 - private best-effort cleanup.
|
||||
pass
|
||||
try:
|
||||
loop.call_soon_threadsafe(loop.stop)
|
||||
except Exception: # noqa: BLE001,S110 - private best-effort cleanup.
|
||||
pass
|
||||
if thread is not None:
|
||||
try:
|
||||
thread.join(timeout=5)
|
||||
except Exception: # noqa: BLE001,S110 - private best-effort cleanup.
|
||||
pass
|
||||
|
||||
|
||||
def _request(
|
||||
model: Any,
|
||||
request: dict[str, Any],
|
||||
send: Callable[[dict[str, Any]], None],
|
||||
max_batch_size: int,
|
||||
supported_skills: frozenset[str],
|
||||
) -> bool:
|
||||
request_id = request.get("id")
|
||||
operation = request.get("operation")
|
||||
if operation == "shutdown":
|
||||
send({"id": request_id, "type": "result", "result": {"closed": True}})
|
||||
return False
|
||||
if operation not in supported_skills:
|
||||
raise ValueError(
|
||||
f"Model does not support the {operation!r} skill. "
|
||||
f"Available skills: {', '.join(sorted(supported_skills))}."
|
||||
)
|
||||
|
||||
started = time.perf_counter()
|
||||
settings = {"max_tokens": int(request.get("max_tokens", 512))}
|
||||
if operation in {"query", "caption"}:
|
||||
image_payload = request.get("image")
|
||||
image = _image(image_payload) if image_payload is not None else None
|
||||
if operation == "query":
|
||||
output = model.query(
|
||||
image=image,
|
||||
question=str(request["question"]),
|
||||
stream=bool(request.get("stream", True)),
|
||||
settings=settings,
|
||||
reasoning=bool(request.get("reasoning", False)),
|
||||
)
|
||||
key = "answer"
|
||||
else:
|
||||
if image is None:
|
||||
raise ValueError("Caption requires an image.")
|
||||
output = model.caption(
|
||||
image=image,
|
||||
length=str(request.get("length", "normal")),
|
||||
stream=bool(request.get("stream", True)),
|
||||
settings=settings,
|
||||
)
|
||||
key = "caption"
|
||||
|
||||
value = output[key]
|
||||
if isinstance(value, str):
|
||||
text = value
|
||||
else:
|
||||
chunks = []
|
||||
for chunk in value:
|
||||
chunk_text = str(chunk)
|
||||
chunks.append(chunk_text)
|
||||
send(
|
||||
{
|
||||
"id": request_id,
|
||||
"type": "chunk",
|
||||
"text": chunk_text,
|
||||
}
|
||||
)
|
||||
text = "".join(chunks)
|
||||
result = {
|
||||
key: text,
|
||||
"elapsed_seconds": time.perf_counter() - started,
|
||||
}
|
||||
if operation == "query" and output.get("reasoning") is not None:
|
||||
result["reasoning"] = output["reasoning"]
|
||||
send({"id": request_id, "type": "result", "result": result})
|
||||
return True
|
||||
|
||||
images = request.get("images")
|
||||
if not isinstance(images, list):
|
||||
raise TypeError(f"{operation} requires an image list.")
|
||||
workers = min(
|
||||
max_batch_size,
|
||||
max(1, int(request.get("parallel_requests", max_batch_size))),
|
||||
)
|
||||
object_prompt = str(request.get("object", "")).strip()
|
||||
if not object_prompt:
|
||||
raise ValueError(f"{operation} requires a non-empty object prompt.")
|
||||
|
||||
if operation == "detect":
|
||||
results = _parallel(
|
||||
images,
|
||||
lambda image: model.detect(image, object_prompt, settings=settings),
|
||||
workers,
|
||||
)
|
||||
elif operation == "point":
|
||||
results = _parallel(
|
||||
images,
|
||||
lambda image: model.point(image, object_prompt, settings=settings),
|
||||
workers,
|
||||
)
|
||||
elif operation == "segment":
|
||||
spatial_refs = request.get("spatial_refs") or None
|
||||
results = _parallel(
|
||||
images,
|
||||
lambda image: model.segment(
|
||||
image,
|
||||
object_prompt,
|
||||
spatial_refs=spatial_refs,
|
||||
stream=False,
|
||||
settings=settings,
|
||||
),
|
||||
workers,
|
||||
)
|
||||
else:
|
||||
raise ValueError(f"Unknown worker operation {operation!r}.")
|
||||
|
||||
send(
|
||||
{
|
||||
"id": request_id,
|
||||
"type": "result",
|
||||
"result": {
|
||||
"items": results,
|
||||
"processed_frames": len(images),
|
||||
"parallel_requests": workers,
|
||||
"elapsed_seconds": time.perf_counter() - started,
|
||||
},
|
||||
}
|
||||
)
|
||||
return True
|
||||
|
||||
|
||||
def main() -> int:
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--host", default="127.0.0.1")
|
||||
parser.add_argument("--port", type=int, required=True)
|
||||
parser.add_argument("--auth-key")
|
||||
parser.add_argument("--model", required=True)
|
||||
parser.add_argument("--device", required=True)
|
||||
parser.add_argument("--max-batch-size", type=int, required=True)
|
||||
parser.add_argument("--kv-cache-pages", type=int, default=0)
|
||||
args = parser.parse_args()
|
||||
|
||||
auth_key = args.auth_key or os.environ.pop("MOONDREAM_WORKER_AUTH", "")
|
||||
if not auth_key:
|
||||
parser.error("worker authentication is missing")
|
||||
connection = Client(
|
||||
(args.host, args.port),
|
||||
authkey=bytes.fromhex(auth_key),
|
||||
)
|
||||
|
||||
def send(value: dict[str, Any]) -> None:
|
||||
connection.send(value)
|
||||
|
||||
send(
|
||||
{
|
||||
"type": "status",
|
||||
"status": "loading",
|
||||
"python": sys.version.split()[0],
|
||||
"platform": platform.platform(),
|
||||
"pid": os.getpid(),
|
||||
}
|
||||
)
|
||||
|
||||
model = None
|
||||
try:
|
||||
import moondream as md
|
||||
|
||||
base_model = _base_model_name(args.model)
|
||||
compatibility_registration = _register_moondream31_if_needed(base_model)
|
||||
telemetry_disabled = _honor_do_not_track()
|
||||
supported_skills = _model_skills(args.model)
|
||||
kwargs: dict[str, Any] = {
|
||||
"local": True,
|
||||
"model": args.model,
|
||||
"device": args.device,
|
||||
"max_batch_size": args.max_batch_size,
|
||||
}
|
||||
if args.kv_cache_pages > 0:
|
||||
kwargs["kv_cache_pages"] = args.kv_cache_pages
|
||||
model = md.vl(**kwargs)
|
||||
try:
|
||||
package_version = version("moondream")
|
||||
except PackageNotFoundError:
|
||||
package_version = "unknown"
|
||||
send(
|
||||
{
|
||||
"type": "status",
|
||||
"status": "ready",
|
||||
"moondream_version": package_version,
|
||||
"compatibility_registration": compatibility_registration,
|
||||
"telemetry_disabled": telemetry_disabled,
|
||||
"skills": sorted(supported_skills),
|
||||
"pid": os.getpid(),
|
||||
}
|
||||
)
|
||||
|
||||
running = True
|
||||
while running:
|
||||
request = connection.recv()
|
||||
request_id = request.get("id") if isinstance(request, dict) else None
|
||||
try:
|
||||
if not isinstance(request, dict):
|
||||
raise TypeError("Worker requests must be dictionaries.")
|
||||
running = _request(
|
||||
model,
|
||||
request,
|
||||
send,
|
||||
args.max_batch_size,
|
||||
supported_skills,
|
||||
)
|
||||
except Exception as exc: # noqa: BLE001 - report request failures over IPC.
|
||||
send(
|
||||
{
|
||||
"id": request_id,
|
||||
"type": "error",
|
||||
"error": f"{type(exc).__name__}: {exc}",
|
||||
"traceback": traceback.format_exc(limit=12),
|
||||
}
|
||||
)
|
||||
except Exception as exc: # noqa: BLE001 - report startup failures over IPC.
|
||||
send(
|
||||
{
|
||||
"type": "fatal",
|
||||
"error": f"{type(exc).__name__}: {exc}",
|
||||
"traceback": traceback.format_exc(limit=20),
|
||||
}
|
||||
)
|
||||
return 1
|
||||
finally:
|
||||
if model is not None:
|
||||
_private_shutdown(model)
|
||||
try:
|
||||
connection.close()
|
||||
except OSError:
|
||||
pass
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
+18
-63
@@ -1,38 +1,10 @@
|
||||
from .moondream import VisionEncoder, TextModel
|
||||
from huggingface_hub import snapshot_download
|
||||
import torch
|
||||
import os
|
||||
import hashlib
|
||||
from torchvision import transforms
|
||||
from pathlib import Path
|
||||
"""Backward-compatible MoonDream node powered by the current Moondream 2."""
|
||||
|
||||
if torch.cuda.is_available():
|
||||
DEVICE = "cuda"
|
||||
DTYPE = torch.float16
|
||||
else:
|
||||
DEVICE = "cpu"
|
||||
DTYPE = torch.float32
|
||||
from .moondream2 import MODEL_ID, MODEL_REVISION, Moondream2Predictor
|
||||
from .runtime import CachedModelNode
|
||||
|
||||
|
||||
output_directory = os.path.join(os.path.dirname(os.path.realpath(__file__)), "output")
|
||||
# Define your local directory where you want to save the files
|
||||
files_for_moondream = Path(__file__).resolve().parent / "files_for__moondream"
|
||||
|
||||
# Check if the directory exists, create if it doesn't (optional)
|
||||
files_for_moondream.mkdir(parents=True, exist_ok=True)
|
||||
image_encoder_cache_path = os.path.join(output_directory, "image_encoder_cache")
|
||||
class MoonDream:
|
||||
def __init__(self):
|
||||
self.model_path = snapshot_download("vikhyatk/moondream1",
|
||||
revision="5cd8d1ecd7e0d8d95222543e1960d340ddffbfef",
|
||||
local_dir=files_for_moondream,
|
||||
force_download=False, # Set to True if you always want to download, regardless of local copy
|
||||
local_files_only=False, # Set to False to allow downloading if not available locally
|
||||
local_dir_use_symlinks="auto" # or set to True/False based on your symlink preference
|
||||
)
|
||||
self.vision_encoder = VisionEncoder(self.model_path)
|
||||
self.text_model = TextModel(self.model_path)
|
||||
|
||||
class MoonDream(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
@@ -42,45 +14,28 @@ class MoonDream:
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "",
|
||||
"default": "Describe this image in detail.",
|
||||
},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"unload_after": ("BOOLEAN", {"default": False})
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
|
||||
FUNCTION = "answer_questions"
|
||||
CATEGORY = "VLM Nodes/Legacy/Model Loaders"
|
||||
|
||||
CATEGORY = "VLM Nodes/MoonDream"
|
||||
|
||||
def process_image(self, image):
|
||||
# Calculate checksum of the image
|
||||
|
||||
image_array = image.numpy() # Convert Tensor to NumPy array
|
||||
image_hash = hashlib.sha256(image_array.tobytes()).hexdigest()
|
||||
image = transforms.ToPILImage()(image[0].permute(2, 0, 1))
|
||||
# Check if `image_encoder_cache/{image_hash}.pt` exists, if so load and return it.
|
||||
# Otherwise, save the encoded image to `image_encoder_cache/{image_hash}.pt` and return it.
|
||||
cache_path = f"{image_encoder_cache_path}/{image_hash}.pt"
|
||||
if os.path.exists(cache_path):
|
||||
return torch.load(cache_path).to(DEVICE, dtype=DTYPE)
|
||||
else:
|
||||
image_vec = self.vision_encoder(image)
|
||||
os.makedirs(image_encoder_cache_path, exist_ok=True)
|
||||
torch.save(image_vec, cache_path)
|
||||
return image_vec.to(DEVICE, dtype=DTYPE)
|
||||
|
||||
def answer_questions(self, image, question):
|
||||
image_embeds = self.process_image(image)
|
||||
full_sentence = self.text_model.answer_question(image_embeds, question)
|
||||
return (full_sentence,)
|
||||
def answer_questions(self, image, question, unload_after=False):
|
||||
predictor = self.get_or_create_model(
|
||||
(MODEL_ID, MODEL_REVISION), Moondream2Predictor
|
||||
)
|
||||
try:
|
||||
return (predictor.generate(image, question),)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
# A dictionary that contains all nodes you want to export with their names
|
||||
NODE_CLASS_MAPPINGS = {"MoonDream": MoonDream}
|
||||
|
||||
# A dictionary that contains the friendly/humanly readable titles for the nodes
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"MoonDream": "MoonDream Node"}
|
||||
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"MoonDream": "MoonDream (Moondream 2)"}
|
||||
|
||||
@@ -0,0 +1,350 @@
|
||||
"""PaLI-Gemma captioning, VQA and official VQ-VAE segmentation."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from PIL import Image, ImageColor, ImageFilter
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ExternalTorchModel,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
external_device_map,
|
||||
hf_download,
|
||||
inference_context,
|
||||
model_device,
|
||||
move_inputs,
|
||||
normalize_hf_model_id,
|
||||
pil_mask_to_tensor,
|
||||
pil_to_tensor,
|
||||
require_quantization_backend,
|
||||
require_module,
|
||||
reserve_external_vram,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
|
||||
PALIGEMMA_MODELS = [
|
||||
"gokaygokay/sd3-long-captioner-v2",
|
||||
"google/paligemma-3b-ft-refcoco-seg-896",
|
||||
"google/paligemma-3b-ft-cococap-448",
|
||||
"google/paligemma-3b-ft-vqav2-448",
|
||||
"google/paligemma-3b-mix-448",
|
||||
"google/paligemma-3b-mix-224",
|
||||
"Custom",
|
||||
]
|
||||
SEGMENT_PATTERN = re.compile(
|
||||
r"<loc(\d{4})><loc(\d{4})><loc(\d{4})><loc(\d{4})>"
|
||||
r"((?:<seg\d{3}>){16})\s*([^;]*)"
|
||||
)
|
||||
|
||||
|
||||
class _Residual(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.net = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(128, 128, 3, padding=1),
|
||||
torch.nn.ReLU(),
|
||||
torch.nn.Conv2d(128, 128, 3, padding=1),
|
||||
torch.nn.ReLU(),
|
||||
torch.nn.Conv2d(128, 128, 1),
|
||||
)
|
||||
|
||||
def forward(self, value):
|
||||
return value + self.net(value)
|
||||
|
||||
|
||||
class PaliMaskDecoder(torch.nn.Module):
|
||||
"""Decoder architecture and weights published with Google's PaliGemma guide."""
|
||||
|
||||
def __init__(self, weights_path: Path):
|
||||
super().__init__()
|
||||
self.decoder = torch.nn.Sequential(
|
||||
torch.nn.Conv2d(512, 128, 1),
|
||||
torch.nn.ReLU(),
|
||||
_Residual(),
|
||||
_Residual(),
|
||||
torch.nn.ConvTranspose2d(128, 128, 4, 2, 1),
|
||||
torch.nn.ReLU(),
|
||||
torch.nn.ConvTranspose2d(128, 64, 4, 2, 1),
|
||||
torch.nn.ReLU(),
|
||||
torch.nn.ConvTranspose2d(64, 32, 4, 2, 1),
|
||||
torch.nn.ReLU(),
|
||||
torch.nn.ConvTranspose2d(32, 16, 4, 2, 1),
|
||||
torch.nn.ReLU(),
|
||||
torch.nn.Conv2d(16, 1, 1),
|
||||
)
|
||||
arrays = np.load(weights_path)
|
||||
self.register_buffer(
|
||||
"codebook",
|
||||
torch.from_numpy(arrays["_vq_vae._embedding"]).float(),
|
||||
)
|
||||
state = self.decoder.state_dict()
|
||||
for key in state:
|
||||
source = f"decoder.{key}"
|
||||
if source not in arrays:
|
||||
raise RuntimeError(f"Official mask decoder is missing {source}.")
|
||||
state[key] = torch.from_numpy(arrays[source])
|
||||
self.decoder.load_state_dict(state)
|
||||
self.eval()
|
||||
|
||||
def forward(self, codes: list[int]) -> torch.Tensor:
|
||||
if len(codes) != 16 or any(code not in range(128) for code in codes):
|
||||
raise ValueError("A PaliGemma mask must contain 16 <seg000..127> tokens.")
|
||||
indices = torch.tensor(codes, device=self.codebook.device)
|
||||
latent = self.codebook[indices].reshape(1, 4, 4, 512)
|
||||
latent = latent.permute(0, 3, 1, 2)
|
||||
# Google's decoder maps its tanh-like output back into [0, 1].
|
||||
return (self.decoder(latent) * 0.5 + 0.5).clamp(0, 1)
|
||||
|
||||
|
||||
def parse_segments(text: str):
|
||||
parsed = []
|
||||
for match in SEGMENT_PATTERN.finditer(text):
|
||||
y1, x1, y2, x2 = (int(match.group(i)) / 1024 for i in range(1, 5))
|
||||
codes = [int(value) for value in re.findall(r"<seg(\d{3})>", match.group(5))]
|
||||
parsed.append(((y1, x1, y2, x2), codes, match.group(6).strip()))
|
||||
return parsed
|
||||
|
||||
|
||||
class PaliPredictor:
|
||||
def __init__(self, repo_id: str, precision: str, quantization: str):
|
||||
transformers = require_module("transformers")
|
||||
external = quantization != "None"
|
||||
if external:
|
||||
# Validate before downloading a multi-gigabyte checkpoint.
|
||||
require_quantization_backend(f"PaLI-Gemma {quantization}")
|
||||
path = snapshot_download(
|
||||
repo_id,
|
||||
f"paligemma/{repo_id.replace('/', '--')}",
|
||||
ignore_patterns=["*.bin", "*.msgpack", "*.h5"],
|
||||
)
|
||||
self.dtype = torch_dtype(precision)
|
||||
self.processor = transformers.AutoProcessor.from_pretrained(path)
|
||||
kwargs: dict[str, Any] = {"dtype": self.dtype}
|
||||
if external:
|
||||
kwargs["quantization_config"] = transformers.BitsAndBytesConfig(
|
||||
load_in_4bit=quantization == "4bit",
|
||||
load_in_8bit=quantization == "8bit",
|
||||
bnb_4bit_compute_dtype=self.dtype,
|
||||
bnb_4bit_quant_type="nf4",
|
||||
bnb_4bit_use_double_quant=True,
|
||||
)
|
||||
kwargs["device_map"] = external_device_map()
|
||||
reserve_external_vram(3 * 1024**3)
|
||||
model = transformers.PaliGemmaForConditionalGeneration.from_pretrained(
|
||||
path, **kwargs
|
||||
).eval()
|
||||
self.handle = (
|
||||
ExternalTorchModel(model, processor=self.processor)
|
||||
if external
|
||||
else ManagedTorchModel(model, processor=self.processor)
|
||||
)
|
||||
self.mask_decoder = None
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
self.mask_decoder = None
|
||||
|
||||
def generate(self, image, prompt, **generation):
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
inputs = self.processor(
|
||||
text=prompt, images=image, return_tensors="pt"
|
||||
)
|
||||
inputs = move_inputs(inputs, device)
|
||||
input_length = inputs["input_ids"].shape[-1]
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
output = model.generate(**inputs, **generation)
|
||||
return self.processor.decode(
|
||||
output[0, input_length:], skip_special_tokens=False
|
||||
).strip()
|
||||
|
||||
def decoder(self):
|
||||
if self.mask_decoder is None:
|
||||
path = hf_download(
|
||||
"big-vision/paligemma",
|
||||
"vae-oid.npz",
|
||||
"paligemma/mask-decoder",
|
||||
repo_type="space",
|
||||
)
|
||||
self.mask_decoder = PaliMaskDecoder(path)
|
||||
return self.mask_decoder
|
||||
|
||||
|
||||
def _render_masks(image: Image.Image, segments, decoder, threshold, blur, color, opacity):
|
||||
width, height = image.size
|
||||
combined = torch.zeros((1, 1, height, width), dtype=torch.float32)
|
||||
for (y1, x1, y2, x2), codes, _label in segments:
|
||||
left = max(0, min(width - 1, round(x1 * width)))
|
||||
top = max(0, min(height - 1, round(y1 * height)))
|
||||
right = max(left + 1, min(width, round(x2 * width)))
|
||||
bottom = max(top + 1, min(height, round(y2 * height)))
|
||||
decoded = decoder(codes)
|
||||
resized = F.interpolate(
|
||||
decoded,
|
||||
size=(bottom - top, right - left),
|
||||
mode="bilinear",
|
||||
align_corners=False,
|
||||
)
|
||||
combined[:, :, top:bottom, left:right] = torch.maximum(
|
||||
combined[:, :, top:bottom, left:right], resized
|
||||
)
|
||||
mask = (combined[0, 0] >= float(threshold)).float().numpy() * 255
|
||||
mask_image = Image.fromarray(mask.astype(np.uint8), "L")
|
||||
if blur > 0:
|
||||
mask_image = mask_image.filter(ImageFilter.GaussianBlur(float(blur)))
|
||||
rgb = ImageColor.getrgb(color)
|
||||
overlay = Image.new("RGBA", image.size, (*rgb, 0))
|
||||
overlay.putalpha(mask_image.point(lambda value: round(value * float(opacity))))
|
||||
visual = Image.alpha_composite(image.convert("RGBA"), overlay).convert("RGB")
|
||||
return mask_image, visual
|
||||
|
||||
|
||||
class Paligemma(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"model_id": (PALIGEMMA_MODELS,),
|
||||
"custom_model_id": ("STRING", {"default": ""}),
|
||||
"task_type": (
|
||||
["Captioning", "Segmentation", "Question Answering"],
|
||||
),
|
||||
"prompt": (
|
||||
"STRING",
|
||||
{"multiline": True, "default": "Describe this image in detail."},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"precision": (["bfloat16", "float32"],),
|
||||
# Retained in place so older workflows keep their widget
|
||||
# indexes. ComfyUI remains the source of truth for placement.
|
||||
"device": (
|
||||
["auto", "cuda", "cpu", "mps", "xpu"],
|
||||
{"default": "auto"},
|
||||
),
|
||||
"quantization": (["None", "8bit", "4bit"],),
|
||||
"mask_threshold": (
|
||||
"FLOAT",
|
||||
{"default": 0.5, "min": 0.0, "max": 1.0},
|
||||
),
|
||||
"mask_blur": ("INT", {"default": 0, "min": 0, "max": 64}),
|
||||
"max_tokens": ("INT", {"default": 256, "min": 1, "max": 2048}),
|
||||
"min_tokens": ("INT", {"default": 0, "min": 0, "max": 512}),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.0, "min": 0.0, "max": 2.0},
|
||||
),
|
||||
"num_beams": ("INT", {"default": 1, "min": 1, "max": 8}),
|
||||
"do_sample": (["False", "True"],),
|
||||
"early_stopping": (["False", "True"],),
|
||||
"fill_mask": (["True", "False"],),
|
||||
"mask_color": ("STRING", {"default": "#00ff88"}),
|
||||
"mask_opacity": (
|
||||
"FLOAT",
|
||||
{"default": 0.5, "min": 0.0, "max": 1.0},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING", "MASK", "IMAGE")
|
||||
RETURN_NAMES = ("description", "mask", "visualization")
|
||||
FUNCTION = "process_task"
|
||||
CATEGORY = "VLM Nodes/Legacy/Model Loaders"
|
||||
|
||||
def process_task(
|
||||
self,
|
||||
image,
|
||||
prompt,
|
||||
task_type,
|
||||
model_id=None,
|
||||
precision="bfloat16",
|
||||
device="auto",
|
||||
quantization="None",
|
||||
custom_model_id="",
|
||||
mask_threshold=0.5,
|
||||
mask_blur=0,
|
||||
max_tokens=256,
|
||||
min_tokens=0,
|
||||
temperature=0.0,
|
||||
num_beams=1,
|
||||
do_sample="False",
|
||||
early_stopping="False",
|
||||
fill_mask="True",
|
||||
mask_color="#00ff88",
|
||||
mask_opacity=0.5,
|
||||
unload_after=False,
|
||||
**_legacy,
|
||||
):
|
||||
del device
|
||||
repo_id = (
|
||||
normalize_hf_model_id(custom_model_id)
|
||||
if model_id == "Custom"
|
||||
else model_id or PALIGEMMA_MODELS[0]
|
||||
)
|
||||
predictor = self.get_or_create_model(
|
||||
(repo_id, precision, quantization),
|
||||
lambda: PaliPredictor(repo_id, precision, quantization),
|
||||
)
|
||||
descriptions, masks, visuals = [], [], []
|
||||
try:
|
||||
for pil_image in tensor_batch_to_pil(image):
|
||||
effective_prompt = (
|
||||
f"segment {prompt}" if task_type == "Segmentation" else prompt
|
||||
)
|
||||
generated = predictor.generate(
|
||||
pil_image,
|
||||
effective_prompt,
|
||||
max_new_tokens=int(max_tokens),
|
||||
min_new_tokens=int(min_tokens),
|
||||
do_sample=do_sample == "True" and float(temperature) > 0,
|
||||
temperature=max(float(temperature), 1e-5),
|
||||
num_beams=int(num_beams),
|
||||
early_stopping=early_stopping == "True",
|
||||
)
|
||||
descriptions.append(generated)
|
||||
if task_type == "Segmentation":
|
||||
segments = parse_segments(generated)
|
||||
if segments:
|
||||
mask, visual = _render_masks(
|
||||
pil_image,
|
||||
segments,
|
||||
predictor.decoder(),
|
||||
mask_threshold,
|
||||
mask_blur,
|
||||
mask_color,
|
||||
mask_opacity if fill_mask == "True" else 0,
|
||||
)
|
||||
else:
|
||||
mask, visual = (
|
||||
Image.new("L", pil_image.size),
|
||||
pil_image,
|
||||
)
|
||||
else:
|
||||
mask, visual = Image.new("L", pil_image.size), pil_image
|
||||
masks.append(pil_mask_to_tensor(mask))
|
||||
visuals.append(pil_to_tensor(visual))
|
||||
return (
|
||||
batch_text(descriptions),
|
||||
torch.cat(masks),
|
||||
torch.cat(visuals),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"Paligemma": Paligemma}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Paligemma": "PaLI-Gemma (Official Segmentation)"}
|
||||
@@ -0,0 +1,42 @@
|
||||
# Hack: string type that is always equal in not equal comparisons
|
||||
class AnyType(str):
|
||||
def __ne__(self, __value: object) -> bool:
|
||||
return False
|
||||
|
||||
|
||||
# Our any instance wants to be a wildcard string
|
||||
any = AnyType("*")
|
||||
|
||||
|
||||
class PlayMusic:
|
||||
@classmethod
|
||||
def INPUT_TYPES(s):
|
||||
return {"required": {
|
||||
"mode": (["always", "on empty queue"], {}),
|
||||
"volume": ("FLOAT", {"min": 0, "max": 1, "step": 0.1, "default": 0.5}),
|
||||
"wave_form": (any,),
|
||||
"sample_rate": ("INT",),
|
||||
}}
|
||||
|
||||
FUNCTION = "nop"
|
||||
INPUT_IS_LIST = True
|
||||
OUTPUT_IS_LIST = (True,)
|
||||
OUTPUT_NODE = True
|
||||
RETURN_TYPES = (any,)
|
||||
|
||||
CATEGORY = "VLM Nodes/Audio"
|
||||
|
||||
def IS_CHANGED(self, **kwargs):
|
||||
return float("NaN")
|
||||
|
||||
def nop(self, mode, volume, wave_form, sample_rate):
|
||||
return {"ui": {"a": wave_form, "b": sample_rate}, "result": (wave_form,)}
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"PlayMusic": PlayMusic,
|
||||
}
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"PlayMusic": "PlayMusic Node",
|
||||
}
|
||||
@@ -0,0 +1,414 @@
|
||||
"""Qwen2-VL with real image/video batches and ComfyUI-aware VRAM handling."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ExternalTorchModel,
|
||||
ManagedTorchModel,
|
||||
accelerator_backend,
|
||||
batch_text,
|
||||
execution_device,
|
||||
external_device_map,
|
||||
inference_context,
|
||||
model_device,
|
||||
move_inputs,
|
||||
require_quantization_backend,
|
||||
require_module,
|
||||
reserve_external_vram,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
|
||||
QWEN2_VL_MODELS = {
|
||||
"Qwen2-VL-2B": "Qwen/Qwen2-VL-2B-Instruct",
|
||||
"Qwen2-VL-7B": "Qwen/Qwen2-VL-7B-Instruct",
|
||||
"Qwen2-VL-72B": "Qwen/Qwen2-VL-72B-Instruct",
|
||||
}
|
||||
# Old workflows used separate AWQ/GPTQ repositories whose integration breaks
|
||||
# across Transformers/AutoGPTQ releases. Resolve those labels to the same base
|
||||
# weights and the maintained bitsandbytes path instead.
|
||||
LEGACY_QUANTIZED_ALIASES = {
|
||||
f"Qwen2-VL-{size}-{quant}": (
|
||||
f"Qwen2-VL-{size}",
|
||||
(
|
||||
"Balanced (8-bit)"
|
||||
if quant.endswith("Int8")
|
||||
else "Maximum Savings (4-bit)"
|
||||
),
|
||||
)
|
||||
for size in ("2B", "7B", "72B")
|
||||
for quant in ("AWQ", "GPTQ-Int4", "GPTQ-Int8")
|
||||
}
|
||||
QWEN2_VL_CHOICES = ("Qwen2-VL-2B", "Qwen2-VL-7B")
|
||||
|
||||
MEMORY_MODES = [
|
||||
"ComfyUI managed (BF16)",
|
||||
"Balanced (8-bit)",
|
||||
"Maximum Savings (4-bit)",
|
||||
"CPU Offload",
|
||||
"Default",
|
||||
]
|
||||
|
||||
ESTIMATED_MODEL_BYTES = {
|
||||
"Qwen2-VL-2B": 5 * 1024**3,
|
||||
"Qwen2-VL-7B": 16 * 1024**3,
|
||||
"Qwen2-VL-72B": 145 * 1024**3,
|
||||
}
|
||||
|
||||
|
||||
def _model_class(transformers):
|
||||
for name in (
|
||||
"Qwen2VLForConditionalGeneration",
|
||||
"AutoModelForImageTextToText",
|
||||
"AutoModelForMultimodalLM",
|
||||
):
|
||||
cls = getattr(transformers, name, None)
|
||||
if cls is not None:
|
||||
return cls
|
||||
raise RuntimeError(
|
||||
"This Transformers version does not include a Qwen2-VL model class."
|
||||
)
|
||||
|
||||
|
||||
def _attention_value(mode: str) -> str:
|
||||
return {
|
||||
"Auto (SDPA)": "sdpa",
|
||||
"Flash Attention 2": "flash_attention_2",
|
||||
"Eager": "eager",
|
||||
}[mode]
|
||||
|
||||
|
||||
class Qwen2VLPredictor:
|
||||
def __init__(
|
||||
self,
|
||||
model_name: str,
|
||||
memory_mode: str,
|
||||
attention_mode: str,
|
||||
min_pixels: int,
|
||||
max_pixels: int,
|
||||
):
|
||||
transformers = require_module("transformers")
|
||||
if model_name in LEGACY_QUANTIZED_ALIASES:
|
||||
model_name, memory_mode = LEGACY_QUANTIZED_ALIASES[model_name]
|
||||
if (
|
||||
attention_mode == "Flash Attention 2"
|
||||
and accelerator_backend(execution_device())
|
||||
not in {"nvidia-cuda", "amd-rocm"}
|
||||
):
|
||||
raise RuntimeError(
|
||||
"Flash Attention 2 requires a supported CUDA or ROCm build. "
|
||||
"Select Auto (SDPA) on Apple Metal, Intel XPU, or CPU."
|
||||
)
|
||||
if memory_mode in {"Balanced (8-bit)", "Maximum Savings (4-bit)"}:
|
||||
# Validate before downloading a multi-gigabyte checkpoint.
|
||||
require_quantization_backend(memory_mode)
|
||||
repo_id = QWEN2_VL_MODELS[model_name]
|
||||
model_path = snapshot_download(
|
||||
repo_id,
|
||||
f"qwen2vl/{model_name}",
|
||||
ignore_patterns=["*.bin"],
|
||||
)
|
||||
self.dtype = torch_dtype("bfloat16")
|
||||
self.processor = transformers.AutoProcessor.from_pretrained(
|
||||
model_path,
|
||||
min_pixels=int(min_pixels),
|
||||
max_pixels=int(max_pixels),
|
||||
)
|
||||
kwargs: dict[str, Any] = {
|
||||
"torch_dtype": self.dtype,
|
||||
"attn_implementation": _attention_value(attention_mode),
|
||||
}
|
||||
external = memory_mode in {
|
||||
"Balanced (8-bit)",
|
||||
"Maximum Savings (4-bit)",
|
||||
"CPU Offload",
|
||||
}
|
||||
|
||||
if memory_mode in {"Balanced (8-bit)", "Maximum Savings (4-bit)"}:
|
||||
kwargs["quantization_config"] = transformers.BitsAndBytesConfig(
|
||||
load_in_8bit=memory_mode == "Balanced (8-bit)",
|
||||
load_in_4bit=memory_mode == "Maximum Savings (4-bit)",
|
||||
bnb_4bit_compute_dtype=self.dtype,
|
||||
bnb_4bit_quant_type="nf4",
|
||||
bnb_4bit_use_double_quant=True,
|
||||
)
|
||||
if external:
|
||||
require_module("accelerate")
|
||||
estimate = ESTIMATED_MODEL_BYTES.get(
|
||||
model_name.split("-AWQ", 1)[0].split("-GPTQ", 1)[0],
|
||||
8 * 1024**3,
|
||||
)
|
||||
reserve_external_vram(
|
||||
estimate // (4 if memory_mode == "Maximum Savings (4-bit)" else 2)
|
||||
)
|
||||
kwargs["device_map"] = external_device_map(
|
||||
allow_auto_offload=memory_mode == "CPU Offload"
|
||||
)
|
||||
|
||||
try:
|
||||
model = _model_class(transformers).from_pretrained(
|
||||
model_path, **kwargs
|
||||
).eval()
|
||||
except ImportError as exc:
|
||||
if attention_mode == "Flash Attention 2":
|
||||
raise RuntimeError(
|
||||
"Flash Attention 2 was selected but flash-attn is not "
|
||||
"installed for this PyTorch accelerator build. Use Auto "
|
||||
"(SDPA), or install a matching flash-attn wheel."
|
||||
) from exc
|
||||
raise
|
||||
|
||||
self.handle = (
|
||||
ExternalTorchModel(model, processor=self.processor)
|
||||
if external
|
||||
else ManagedTorchModel(model, processor=self.processor)
|
||||
)
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
def _generate_messages(
|
||||
self,
|
||||
messages,
|
||||
*,
|
||||
max_new_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
) -> str:
|
||||
process_vision_info = require_module(
|
||||
"qwen_vl_utils", "qwen-vl-utils"
|
||||
).process_vision_info
|
||||
text = self.processor.apply_chat_template(
|
||||
messages, tokenize=False, add_generation_prompt=True
|
||||
)
|
||||
image_inputs, video_inputs = process_vision_info(messages)
|
||||
inputs = self.processor(
|
||||
text=[text],
|
||||
images=image_inputs,
|
||||
videos=video_inputs,
|
||||
padding=True,
|
||||
return_tensors="pt",
|
||||
)
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
inputs = move_inputs(inputs, device)
|
||||
generation: dict[str, Any] = {
|
||||
"max_new_tokens": int(max_new_tokens),
|
||||
"do_sample": float(temperature) > 0.0,
|
||||
}
|
||||
if generation["do_sample"]:
|
||||
generation.update(
|
||||
temperature=float(temperature), top_p=float(top_p)
|
||||
)
|
||||
tokenizer = getattr(self.processor, "tokenizer", None)
|
||||
if tokenizer is not None:
|
||||
generation["pad_token_id"] = tokenizer.pad_token_id
|
||||
generation["eos_token_id"] = tokenizer.eos_token_id
|
||||
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
output_ids = model.generate(**inputs, **generation)
|
||||
trimmed = [
|
||||
output[len(input_ids) :]
|
||||
for input_ids, output in zip(inputs["input_ids"], output_ids)
|
||||
]
|
||||
return self.processor.batch_decode(
|
||||
trimmed,
|
||||
skip_special_tokens=True,
|
||||
clean_up_tokenization_spaces=False,
|
||||
)[0].strip()
|
||||
|
||||
def generate_images(
|
||||
self, images, prompt, max_new_tokens, temperature, top_p
|
||||
) -> str:
|
||||
results = []
|
||||
for image in tensor_batch_to_pil(images):
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "image", "image": image},
|
||||
{"type": "text", "text": prompt},
|
||||
],
|
||||
}
|
||||
]
|
||||
results.append(
|
||||
self._generate_messages(
|
||||
messages,
|
||||
max_new_tokens=max_new_tokens,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
)
|
||||
)
|
||||
return batch_text(results)
|
||||
|
||||
def generate_video(
|
||||
self,
|
||||
primary_image,
|
||||
frames,
|
||||
prompt,
|
||||
max_new_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
fps,
|
||||
) -> str:
|
||||
# The still IMAGE socket is required by ComfyUI for backwards
|
||||
# compatibility, but a connected frame batch is the visual source for
|
||||
# video inference. Mixing both causes small VLMs to answer from the
|
||||
# still and ignore temporal content.
|
||||
del primary_image
|
||||
frame_list = tensor_batch_to_pil(frames)
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{
|
||||
"type": "video",
|
||||
"video": frame_list,
|
||||
"fps": float(fps),
|
||||
},
|
||||
{
|
||||
"type": "text",
|
||||
"text": (
|
||||
f"The video frames are sampled at {float(fps):g} "
|
||||
f"FPS.\n\n{prompt}"
|
||||
),
|
||||
},
|
||||
],
|
||||
}
|
||||
]
|
||||
return self._generate_messages(
|
||||
messages,
|
||||
max_new_tokens=max_new_tokens,
|
||||
temperature=temperature,
|
||||
top_p=top_p,
|
||||
)
|
||||
|
||||
|
||||
class Qwen2VLNode(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"text_input": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "Describe this image in detail.",
|
||||
},
|
||||
),
|
||||
"model_name": (list(QWEN2_VL_CHOICES),),
|
||||
"memory_mode": (
|
||||
MEMORY_MODES,
|
||||
{"default": "ComfyUI managed (BF16)"},
|
||||
),
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 512, "min": 1, "max": 8192},
|
||||
),
|
||||
"temperature": (
|
||||
"FLOAT",
|
||||
{"default": 0.2, "min": 0.0, "max": 2.0, "step": 0.1},
|
||||
),
|
||||
"top_p": (
|
||||
"FLOAT",
|
||||
{"default": 0.9, "min": 0.0, "max": 1.0, "step": 0.05},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"image": ("IMAGE",),
|
||||
"video_frames": ("IMAGE",),
|
||||
"fps": (
|
||||
"FLOAT",
|
||||
{"default": 1.0, "min": 0.1, "max": 60.0, "step": 0.1},
|
||||
),
|
||||
"attention_mode": (
|
||||
["Auto (SDPA)", "Flash Attention 2", "Eager"],
|
||||
{"default": "Auto (SDPA)"},
|
||||
),
|
||||
"min_pixels": (
|
||||
"INT",
|
||||
{"default": 256 * 28 * 28, "min": 28 * 28},
|
||||
),
|
||||
"max_pixels": (
|
||||
"INT",
|
||||
{"default": 1280 * 28 * 28, "min": 28 * 28},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "generate"
|
||||
CATEGORY = "VLM Nodes/Legacy/Model Loaders"
|
||||
|
||||
def generate(
|
||||
self,
|
||||
text_input,
|
||||
model_name,
|
||||
memory_mode="ComfyUI managed (BF16)",
|
||||
max_new_tokens=512,
|
||||
temperature=0.2,
|
||||
top_p=0.9,
|
||||
image=None,
|
||||
video_frames=None,
|
||||
fps=1.0,
|
||||
attention_mode="Auto (SDPA)",
|
||||
min_pixels=256 * 28 * 28,
|
||||
max_pixels=1280 * 28 * 28,
|
||||
unload_after=False,
|
||||
):
|
||||
if min_pixels > max_pixels:
|
||||
raise ValueError("min_pixels cannot be greater than max_pixels.")
|
||||
if image is None and video_frames is None:
|
||||
raise ValueError("Connect either image or video_frames.")
|
||||
key = (
|
||||
model_name,
|
||||
memory_mode,
|
||||
attention_mode,
|
||||
int(min_pixels),
|
||||
int(max_pixels),
|
||||
)
|
||||
predictor = self.get_or_create_model(
|
||||
key,
|
||||
lambda: Qwen2VLPredictor(
|
||||
model_name,
|
||||
memory_mode,
|
||||
attention_mode,
|
||||
min_pixels,
|
||||
max_pixels,
|
||||
),
|
||||
)
|
||||
try:
|
||||
if video_frames is None:
|
||||
result = predictor.generate_images(
|
||||
image,
|
||||
text_input,
|
||||
max_new_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
)
|
||||
else:
|
||||
result = predictor.generate_video(
|
||||
image,
|
||||
video_frames,
|
||||
text_input,
|
||||
max_new_tokens,
|
||||
temperature,
|
||||
top_p,
|
||||
fps,
|
||||
)
|
||||
return (result,)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"Qwen2VLNode": Qwen2VLNode}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Qwen2VLNode": "Qwen2-VL"}
|
||||
+1159
File diff suppressed because it is too large
Load Diff
+539
@@ -0,0 +1,539 @@
|
||||
"""Prompt-seeded SAM2.1 image-batch/video segmentation and tracking."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import math
|
||||
from dataclasses import dataclass
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
|
||||
from .geometry import bbox_from_mask, deterministic_color
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
inference_context,
|
||||
model_device,
|
||||
require_module,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
from .vision_types import (
|
||||
VLM_DETECTIONS,
|
||||
VLM_TRACKS,
|
||||
Detection,
|
||||
DetectionSequence,
|
||||
Track,
|
||||
TrackSequence,
|
||||
)
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class Sam2Spec:
|
||||
model_id: str
|
||||
cache_name: str
|
||||
|
||||
|
||||
SAM2_MODELS = {
|
||||
"SAM2.1 Hiera Tiny (fast)": Sam2Spec(
|
||||
"facebook/sam2.1-hiera-tiny", "sam2.1-hiera-tiny"
|
||||
),
|
||||
"SAM2.1 Hiera Small": Sam2Spec("facebook/sam2.1-hiera-small", "sam2.1-hiera-small"),
|
||||
"SAM2.1 Hiera Base+": Sam2Spec(
|
||||
"facebook/sam2.1-hiera-base-plus", "sam2.1-hiera-base-plus"
|
||||
),
|
||||
"SAM2.1 Hiera Large": Sam2Spec("facebook/sam2.1-hiera-large", "sam2.1-hiera-large"),
|
||||
}
|
||||
|
||||
|
||||
def _core_box(value: dict[str, Any]) -> tuple[float, float, float, float]:
|
||||
try:
|
||||
x, y = float(value["x"]), float(value["y"])
|
||||
width, height = float(value["width"]), float(value["height"])
|
||||
except (KeyError, TypeError, ValueError) as exc:
|
||||
raise ValueError(
|
||||
"BOUNDING_BOX must contain numeric x, y, width, and height."
|
||||
) from exc
|
||||
if width <= 0 or height <= 0:
|
||||
raise ValueError("BOUNDING_BOX width and height must be positive.")
|
||||
return x, y, x + width, y + height
|
||||
|
||||
|
||||
def _core_box_frames(value: Any) -> list[list[dict[str, Any]]]:
|
||||
"""Normalize core dict/flat/nested BOUNDING_BOX values to frame lists."""
|
||||
|
||||
if value is None:
|
||||
return []
|
||||
if isinstance(value, dict):
|
||||
return [[value]]
|
||||
if not isinstance(value, list):
|
||||
raise TypeError("BOUNDING_BOX must be a dict, list of dicts, or frame list.")
|
||||
if not value:
|
||||
return []
|
||||
if all(isinstance(item, dict) for item in value):
|
||||
return [value]
|
||||
if all(
|
||||
isinstance(frame, list) and all(isinstance(item, dict) for item in frame)
|
||||
for frame in value
|
||||
):
|
||||
return value
|
||||
raise TypeError("BOUNDING_BOX contains an unsupported nested value.")
|
||||
|
||||
|
||||
def _box_label(value: dict[str, Any]) -> str | None:
|
||||
label = value.get("label")
|
||||
if isinstance(label, str) and label.strip():
|
||||
return label.strip()
|
||||
metadata = value.get("metadata")
|
||||
if isinstance(metadata, dict):
|
||||
label = metadata.get("label")
|
||||
if isinstance(label, str) and label.strip():
|
||||
return label.strip()
|
||||
return None
|
||||
|
||||
|
||||
def seed_boxes(
|
||||
*,
|
||||
width: int,
|
||||
height: int,
|
||||
frame_index: int,
|
||||
detections: DetectionSequence | None,
|
||||
bounding_box: Any,
|
||||
) -> tuple[list[list[float]], list[int], dict[int, str | None]]:
|
||||
boxes: list[list[float]] = []
|
||||
object_ids: list[int] = []
|
||||
labels: dict[int, str | None] = {}
|
||||
if detections is not None:
|
||||
if not isinstance(detections, DetectionSequence):
|
||||
raise TypeError("detections must be a VLM Detection Sequence.")
|
||||
if detections.width != width or detections.height != height:
|
||||
raise ValueError(
|
||||
"Detection dimensions must exactly match the SAM2 video frames."
|
||||
)
|
||||
frame = detections.frame(frame_index)
|
||||
if frame is None and len(detections.frames) == 1:
|
||||
# A detector run over a selected single image is an explicit seed
|
||||
# annotation and may be applied to any chosen video frame.
|
||||
frame = detections.frames[0]
|
||||
elif frame is None and detections.frames:
|
||||
raise ValueError(
|
||||
f"Detections do not contain the requested seed frame {frame_index}."
|
||||
)
|
||||
for index, detection in enumerate(frame.detections if frame else (), 1):
|
||||
track_id = detection.track_id
|
||||
object_id = int(track_id if track_id is not None else index)
|
||||
while object_id in object_ids:
|
||||
object_id += 1
|
||||
x1, y1, x2, y2 = detection.bbox_xyxy
|
||||
boxes.append(
|
||||
[
|
||||
min(width, max(0.0, x1)),
|
||||
min(height, max(0.0, y1)),
|
||||
min(width, max(0.0, x2)),
|
||||
min(height, max(0.0, y2)),
|
||||
]
|
||||
)
|
||||
object_ids.append(object_id)
|
||||
labels[object_id] = detection.label
|
||||
box_frames = _core_box_frames(bounding_box)
|
||||
if len(box_frames) == 1:
|
||||
selected_boxes = box_frames[0]
|
||||
elif box_frames and frame_index < len(box_frames):
|
||||
selected_boxes = box_frames[frame_index]
|
||||
elif box_frames:
|
||||
raise ValueError(
|
||||
f"BOUNDING_BOX has {len(box_frames)} frames but seed_frame is "
|
||||
f"{frame_index}."
|
||||
)
|
||||
else:
|
||||
selected_boxes = []
|
||||
for value in selected_boxes:
|
||||
x1, y1, x2, y2 = _core_box(value)
|
||||
object_id = max(object_ids, default=0) + 1
|
||||
boxes.append(
|
||||
[
|
||||
min(width, max(0.0, x1)),
|
||||
min(height, max(0.0, y1)),
|
||||
min(width, max(0.0, x2)),
|
||||
min(height, max(0.0, y2)),
|
||||
]
|
||||
)
|
||||
object_ids.append(object_id)
|
||||
labels[object_id] = _box_label(value)
|
||||
valid = []
|
||||
for box, object_id in zip(boxes, object_ids):
|
||||
if box[2] > box[0] and box[3] > box[1]:
|
||||
valid.append((box, object_id))
|
||||
return (
|
||||
[box for box, _object_id in valid],
|
||||
[object_id for _box, object_id in valid],
|
||||
labels,
|
||||
)
|
||||
|
||||
|
||||
def _normalize_processed_masks(value: torch.Tensor) -> torch.Tensor:
|
||||
masks = value.detach().to(device="cpu")
|
||||
if masks.ndim == 4 and masks.shape[1] == 1:
|
||||
masks = masks[:, 0]
|
||||
elif masks.ndim == 4 and masks.shape[0] == 1:
|
||||
masks = masks[0]
|
||||
if masks.ndim == 2:
|
||||
masks = masks.unsqueeze(0)
|
||||
if masks.ndim != 3:
|
||||
raise RuntimeError(
|
||||
f"SAM2 returned an unsupported mask shape {tuple(masks.shape)}."
|
||||
)
|
||||
return masks if masks.dtype == torch.bool else masks > 0.5
|
||||
|
||||
|
||||
class Sam2VideoPredictor:
|
||||
def __init__(self, spec: Sam2Spec, precision: str):
|
||||
transformers = require_module("transformers")
|
||||
if not hasattr(transformers, "Sam2VideoModel"):
|
||||
raise RuntimeError(
|
||||
"SAM2 video requires Transformers with Sam2VideoModel support."
|
||||
)
|
||||
model_path = snapshot_download(
|
||||
spec.model_id,
|
||||
spec.cache_name,
|
||||
ignore_patterns=["*.pt", "*.bin", "*.onnx", "*.tflite"],
|
||||
)
|
||||
self.processor = transformers.Sam2VideoProcessor.from_pretrained(model_path)
|
||||
self.dtype = torch_dtype(precision)
|
||||
model = transformers.Sam2VideoModel.from_pretrained(
|
||||
model_path, dtype=self.dtype
|
||||
)
|
||||
model.eval()
|
||||
self.handle = ManagedTorchModel(model, processor=self.processor)
|
||||
self.spec = spec
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
|
||||
def propagate(
|
||||
self,
|
||||
images: torch.Tensor,
|
||||
*,
|
||||
seed_frame: int,
|
||||
fps: float,
|
||||
detections: DetectionSequence | None,
|
||||
bounding_box: Any,
|
||||
seed_mask: torch.Tensor | None,
|
||||
mask_threshold: float,
|
||||
keep_video_on_cpu: bool,
|
||||
mask_output: str,
|
||||
render_preview: bool,
|
||||
) -> tuple[TrackSequence, torch.Tensor, torch.Tensor, torch.Tensor]:
|
||||
if not math.isfinite(fps) or fps <= 0:
|
||||
raise ValueError("fps must be finite and positive.")
|
||||
if mask_output not in {"union_only", "union_and_objects"}:
|
||||
raise ValueError(f"Unsupported mask_output mode {mask_output!r}.")
|
||||
pil_images = tensor_batch_to_pil(images)
|
||||
if not pil_images:
|
||||
raise ValueError("SAM2 requires at least one image.")
|
||||
if not 0 <= seed_frame < len(pil_images):
|
||||
raise ValueError(
|
||||
f"seed_frame {seed_frame} is outside the {len(pil_images)}-frame batch."
|
||||
)
|
||||
width, height = pil_images[0].size
|
||||
if any(image.size != (width, height) for image in pil_images):
|
||||
raise ValueError("Every video frame must have identical dimensions.")
|
||||
|
||||
boxes, object_ids, labels = seed_boxes(
|
||||
width=width,
|
||||
height=height,
|
||||
frame_index=seed_frame,
|
||||
detections=detections,
|
||||
bounding_box=bounding_box,
|
||||
)
|
||||
masks_for_seed = None
|
||||
if not boxes and seed_mask is not None:
|
||||
masks_for_seed = seed_mask.detach().to(device="cpu", dtype=torch.float32)
|
||||
if masks_for_seed.ndim == 2:
|
||||
masks_for_seed = masks_for_seed.unsqueeze(0)
|
||||
if masks_for_seed.ndim != 3 or tuple(masks_for_seed.shape[-2:]) != (
|
||||
height,
|
||||
width,
|
||||
):
|
||||
raise ValueError("seed_mask must have shape [objects, height, width].")
|
||||
object_ids = list(range(1, masks_for_seed.shape[0] + 1))
|
||||
labels = {object_id: None for object_id in object_ids}
|
||||
if not object_ids:
|
||||
raise ValueError(
|
||||
"Connect detections, a BOUNDING_BOX, or at least one seed mask."
|
||||
)
|
||||
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
state_device = torch.device("cpu") if keep_video_on_cpu else device
|
||||
processing_device = state_device if keep_video_on_cpu else device
|
||||
object_count = len(object_ids)
|
||||
union = torch.zeros((len(pil_images), height, width), dtype=torch.float32)
|
||||
if mask_output == "union_and_objects":
|
||||
individual = torch.zeros(
|
||||
(len(pil_images) * object_count, height, width),
|
||||
dtype=torch.float32,
|
||||
)
|
||||
else:
|
||||
individual = torch.zeros((0, height, width), dtype=torch.float32)
|
||||
source_preview = images.detach().to(device="cpu", dtype=torch.float32)
|
||||
preview = source_preview.clone() if render_preview else source_preview
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
session = self.processor.init_video_session(
|
||||
video=pil_images,
|
||||
inference_device=device,
|
||||
inference_state_device=state_device,
|
||||
processing_device=processing_device,
|
||||
video_storage_device=state_device,
|
||||
max_vision_features_cache_size=1,
|
||||
dtype=self.dtype,
|
||||
)
|
||||
seed_kwargs: dict[str, Any] = {
|
||||
"inference_session": session,
|
||||
"frame_idx": int(seed_frame),
|
||||
"obj_ids": object_ids,
|
||||
}
|
||||
if boxes:
|
||||
seed_kwargs["input_boxes"] = [boxes]
|
||||
else:
|
||||
seed_kwargs["input_masks"] = [
|
||||
masks_for_seed[index] for index in range(len(object_ids))
|
||||
]
|
||||
self.processor.add_inputs_to_inference_session(**seed_kwargs)
|
||||
|
||||
per_object: dict[int, dict[int, Detection]] = {
|
||||
object_id: {} for object_id in object_ids
|
||||
}
|
||||
|
||||
def record_output(output):
|
||||
frame_index = int(output.frame_idx)
|
||||
processed = self.processor.post_process_masks(
|
||||
[output.pred_masks],
|
||||
original_sizes=[[height, width]],
|
||||
mask_threshold=float(mask_threshold),
|
||||
binarize=True,
|
||||
)[0]
|
||||
processed = _normalize_processed_masks(processed)
|
||||
current_ids = list(getattr(session, "obj_ids", object_ids))
|
||||
if render_preview:
|
||||
# The Transformers iterator may revisit the seed frame in
|
||||
# both directions. Rebuild that frame from the immutable
|
||||
# source so opacity is never accumulated across visits.
|
||||
preview[frame_index].copy_(source_preview[frame_index])
|
||||
for object_index, object_id in enumerate(current_ids):
|
||||
if object_index >= processed.shape[0]:
|
||||
continue
|
||||
mask = processed[object_index]
|
||||
float_mask = mask.to(dtype=torch.float32)
|
||||
union[frame_index] = torch.maximum(union[frame_index], float_mask)
|
||||
if mask_output == "union_and_objects":
|
||||
individual[frame_index * object_count + object_index] = (
|
||||
float_mask
|
||||
)
|
||||
if render_preview:
|
||||
color = torch.tensor(
|
||||
deterministic_color(object_id),
|
||||
dtype=preview.dtype,
|
||||
).div(255.0)
|
||||
alpha = float_mask.unsqueeze(-1) * 0.45
|
||||
preview[frame_index] = (
|
||||
preview[frame_index] * (1.0 - alpha) + color * alpha
|
||||
)
|
||||
bbox = bbox_from_mask(mask)
|
||||
if bbox is None:
|
||||
continue
|
||||
per_object.setdefault(int(object_id), {})[frame_index] = Detection(
|
||||
bbox_xyxy=bbox,
|
||||
label=labels.get(int(object_id)),
|
||||
frame_index=frame_index,
|
||||
timestamp=frame_index / fps,
|
||||
track_id=int(object_id),
|
||||
source=self.spec.model_id,
|
||||
metadata={
|
||||
"observation": (
|
||||
"detected"
|
||||
if frame_index == seed_frame
|
||||
else "propagated"
|
||||
),
|
||||
**(
|
||||
{
|
||||
"mask_batch_index": (
|
||||
frame_index * object_count + object_index
|
||||
)
|
||||
}
|
||||
if mask_output == "union_and_objects"
|
||||
else {"object_mask_output": "disabled"}
|
||||
),
|
||||
},
|
||||
)
|
||||
|
||||
# SAM2 does not consider prompt insertion itself an inference pass.
|
||||
# Running the conditioned frame establishes the track start before
|
||||
# either propagation direction is requested.
|
||||
record_output(model(inference_session=session, frame_idx=seed_frame))
|
||||
for output in model.propagate_in_video_iterator(
|
||||
inference_session=session,
|
||||
start_frame_idx=seed_frame,
|
||||
show_progress_bar=False,
|
||||
):
|
||||
record_output(output)
|
||||
if seed_frame > 0:
|
||||
for output in model.propagate_in_video_iterator(
|
||||
inference_session=session,
|
||||
start_frame_idx=seed_frame,
|
||||
reverse=True,
|
||||
show_progress_bar=False,
|
||||
):
|
||||
record_output(output)
|
||||
|
||||
tracks = tuple(
|
||||
Track(
|
||||
track_id=object_id,
|
||||
detections=tuple(
|
||||
records[frame_index] for frame_index in sorted(records)
|
||||
),
|
||||
label=labels.get(object_id),
|
||||
source=self.spec.model_id,
|
||||
metadata={"backend": "transformers-sam2-video"},
|
||||
)
|
||||
for object_id, records in sorted(per_object.items())
|
||||
if records
|
||||
)
|
||||
track_sequence = TrackSequence(
|
||||
width=width,
|
||||
height=height,
|
||||
tracks=tracks,
|
||||
frame_count=len(pil_images),
|
||||
fps=fps,
|
||||
source=self.spec.model_id,
|
||||
metadata={
|
||||
"seed_frame": seed_frame,
|
||||
"object_ids": object_ids,
|
||||
"mask_output": mask_output,
|
||||
"mask_order": (
|
||||
"frame_major_object_minor"
|
||||
if mask_output == "union_and_objects"
|
||||
else None
|
||||
),
|
||||
},
|
||||
)
|
||||
if render_preview:
|
||||
preview.clamp_(0, 1)
|
||||
return track_sequence, union, individual, preview
|
||||
|
||||
|
||||
class VLMSAM2VideoSegmentation(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"images": ("IMAGE",),
|
||||
"model": (tuple(SAM2_MODELS),),
|
||||
"seed_frame": ("INT", {"default": 0, "min": 0, "max": 1000000}),
|
||||
"fps": (
|
||||
"FLOAT",
|
||||
{
|
||||
"default": 24.0,
|
||||
"min": 0.001,
|
||||
"max": 1000.0,
|
||||
"step": 0.001,
|
||||
},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"detections": (VLM_DETECTIONS,),
|
||||
"bounding_box": ("BOUNDING_BOX",),
|
||||
"seed_mask": ("MASK",),
|
||||
"mask_threshold": (
|
||||
"FLOAT",
|
||||
{"default": 0.0, "min": -10.0, "max": 10.0, "step": 0.05},
|
||||
),
|
||||
"precision": (("auto", "bfloat16", "float16", "float32"),),
|
||||
"keep_video_on_cpu": ("BOOLEAN", {"default": True}),
|
||||
"mask_output": (
|
||||
("union_only", "union_and_objects"),
|
||||
{
|
||||
"default": "union_only",
|
||||
"tooltip": (
|
||||
"Per-object full-resolution masks can be very large."
|
||||
),
|
||||
},
|
||||
),
|
||||
"render_preview": (
|
||||
"BOOLEAN",
|
||||
{
|
||||
"default": True,
|
||||
"tooltip": (
|
||||
"Disable to return the input batch without another "
|
||||
"full-size overlay copy."
|
||||
),
|
||||
},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = (VLM_TRACKS, "STRING", "MASK", "MASK", "IMAGE")
|
||||
RETURN_NAMES = (
|
||||
"tracks",
|
||||
"json",
|
||||
"union_masks",
|
||||
"object_masks",
|
||||
"preview",
|
||||
)
|
||||
FUNCTION = "segment"
|
||||
CATEGORY = "VLM Nodes/Vision/Segmentation"
|
||||
DESCRIPTION = (
|
||||
"Track detection boxes or masks through an IMAGE batch with SAM2.1. "
|
||||
"Connect the fps output of Get Video Components for correct timestamps."
|
||||
)
|
||||
|
||||
def segment(
|
||||
self,
|
||||
images,
|
||||
model,
|
||||
seed_frame,
|
||||
fps,
|
||||
detections=None,
|
||||
bounding_box=None,
|
||||
seed_mask=None,
|
||||
mask_threshold=0.0,
|
||||
precision="auto",
|
||||
keep_video_on_cpu=True,
|
||||
mask_output="union_only",
|
||||
render_preview=True,
|
||||
unload_after=False,
|
||||
):
|
||||
fps_value = float(fps)
|
||||
if not math.isfinite(fps_value) or fps_value <= 0:
|
||||
raise ValueError("fps must be finite and positive.")
|
||||
spec = SAM2_MODELS[model]
|
||||
predictor = self.get_or_create_model(
|
||||
(spec.model_id, precision),
|
||||
lambda: Sam2VideoPredictor(spec, precision),
|
||||
)
|
||||
try:
|
||||
tracks, union, individual, preview = predictor.propagate(
|
||||
images,
|
||||
seed_frame=int(seed_frame),
|
||||
fps=fps_value,
|
||||
detections=detections,
|
||||
bounding_box=bounding_box,
|
||||
seed_mask=seed_mask,
|
||||
mask_threshold=float(mask_threshold),
|
||||
keep_video_on_cpu=bool(keep_video_on_cpu),
|
||||
mask_output=mask_output,
|
||||
render_preview=bool(render_preview),
|
||||
)
|
||||
return tracks, tracks.to_json(indent=2), union, individual, preview
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"VLMSAM2VideoSegmentation": VLMSAM2VideoSegmentation,
|
||||
}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"VLMSAM2VideoSegmentation": "VLM SAM2.1 Video Segmentation",
|
||||
}
|
||||
@@ -0,0 +1,560 @@
|
||||
"""Guarded adapters for ComfyUI core ``SAM3_TRACK_DATA`` payloads.
|
||||
|
||||
Core SAM3 keeps masks bit-packed for memory efficiency. This module preserves
|
||||
that payload untouched and emits small canonical ``VLM_TRACKS`` metadata with
|
||||
mask references instead of embedding dense masks in JSON.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import math
|
||||
from collections.abc import Iterator, Mapping, Sequence
|
||||
from dataclasses import dataclass
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
|
||||
from .geometry import bbox_from_mask, clip_box
|
||||
from .vision_types import (
|
||||
VLM_DETECTIONS,
|
||||
VLM_TRACKS,
|
||||
Detection,
|
||||
DetectionSequence,
|
||||
Track,
|
||||
TrackSequence,
|
||||
)
|
||||
|
||||
SAM3_TRACK_DATA = "SAM3_TRACK_DATA"
|
||||
SAM3_ADAPTER_SOURCE = "comfyui-core-sam3"
|
||||
_REQUIRED_KEYS = frozenset({"packed_masks", "n_frames", "scores", "orig_size"})
|
||||
|
||||
|
||||
@dataclass(frozen=True, slots=True)
|
||||
class SAM3TrackLayout:
|
||||
n_frames: int
|
||||
n_objects: int
|
||||
mask_height: int
|
||||
mask_width: int
|
||||
orig_height: int
|
||||
orig_width: int
|
||||
scores: tuple[float | None, ...]
|
||||
|
||||
|
||||
@dataclass(frozen=True, slots=True)
|
||||
class _SeedIdentity:
|
||||
track_id: int | None
|
||||
label: str | None
|
||||
text: str | None
|
||||
score: float | None
|
||||
source: str | None
|
||||
|
||||
|
||||
def _integer(value: Any, name: str, *, minimum: int = 0) -> int:
|
||||
if isinstance(value, bool) or not isinstance(value, int):
|
||||
raise TypeError(f"{name} must be an integer.")
|
||||
if value < minimum:
|
||||
raise ValueError(f"{name} must be at least {minimum}.")
|
||||
return value
|
||||
|
||||
|
||||
def _scores(
|
||||
values: Any,
|
||||
*,
|
||||
n_objects: int,
|
||||
) -> tuple[float | None, ...]:
|
||||
if isinstance(values, torch.Tensor):
|
||||
if values.ndim != 1:
|
||||
raise ValueError("SAM3 scores tensor must have shape [objects].")
|
||||
items = values.detach().cpu().tolist()
|
||||
elif isinstance(values, Sequence) and not isinstance(values, (str, bytes)):
|
||||
items = list(values)
|
||||
else:
|
||||
raise TypeError("SAM3 scores must be a one-dimensional sequence.")
|
||||
if len(items) > n_objects:
|
||||
raise ValueError("SAM3 scores contain more entries than mask objects.")
|
||||
parsed: list[float | None] = []
|
||||
for value in items:
|
||||
if value is None:
|
||||
parsed.append(None)
|
||||
continue
|
||||
score = float(value)
|
||||
if not math.isfinite(score) or not 0.0 <= score <= 1.0:
|
||||
raise ValueError("SAM3 scores must be finite values from 0 to 1.")
|
||||
parsed.append(score)
|
||||
parsed.extend([None] * (n_objects - len(parsed)))
|
||||
return tuple(parsed)
|
||||
|
||||
|
||||
def validate_sam3_track_data(track_data: Any) -> SAM3TrackLayout:
|
||||
"""Validate the private core payload before interpreting its bit layout."""
|
||||
|
||||
if not isinstance(track_data, Mapping):
|
||||
raise TypeError("SAM3_TRACK_DATA must be a mapping.")
|
||||
missing = sorted(_REQUIRED_KEYS - set(track_data))
|
||||
if missing:
|
||||
raise ValueError(
|
||||
"SAM3_TRACK_DATA is missing required keys: " + ", ".join(missing)
|
||||
)
|
||||
|
||||
n_frames = _integer(track_data["n_frames"], "n_frames")
|
||||
orig_size = track_data["orig_size"]
|
||||
if not isinstance(orig_size, (tuple, list)) or len(orig_size) != 2:
|
||||
raise TypeError("SAM3 orig_size must be (height, width).")
|
||||
orig_height = _integer(orig_size[0], "orig_height", minimum=1)
|
||||
orig_width = _integer(orig_size[1], "orig_width", minimum=1)
|
||||
|
||||
packed = track_data["packed_masks"]
|
||||
if packed is None:
|
||||
scores = _scores(track_data["scores"], n_objects=0)
|
||||
return SAM3TrackLayout(
|
||||
n_frames=n_frames,
|
||||
n_objects=0,
|
||||
mask_height=0,
|
||||
mask_width=0,
|
||||
orig_height=orig_height,
|
||||
orig_width=orig_width,
|
||||
scores=scores,
|
||||
)
|
||||
if not isinstance(packed, torch.Tensor):
|
||||
raise TypeError("SAM3 packed_masks must be a torch.Tensor or None.")
|
||||
if packed.dtype != torch.uint8:
|
||||
raise TypeError("SAM3 packed_masks must use torch.uint8.")
|
||||
if packed.ndim != 4:
|
||||
raise ValueError(
|
||||
"SAM3 packed_masks must have shape [frames, objects, height, packed_width]."
|
||||
)
|
||||
if packed.shape[0] != n_frames:
|
||||
raise ValueError("SAM3 n_frames does not match packed_masks.")
|
||||
n_objects = int(packed.shape[1])
|
||||
mask_height = int(packed.shape[2])
|
||||
packed_width = int(packed.shape[3])
|
||||
if n_objects < 1 or mask_height < 1 or packed_width < 1:
|
||||
raise ValueError("SAM3 packed_masks dimensions must be positive.")
|
||||
scores = _scores(track_data["scores"], n_objects=n_objects)
|
||||
return SAM3TrackLayout(
|
||||
n_frames=n_frames,
|
||||
n_objects=n_objects,
|
||||
mask_height=mask_height,
|
||||
mask_width=packed_width * 8,
|
||||
orig_height=orig_height,
|
||||
orig_width=orig_width,
|
||||
scores=scores,
|
||||
)
|
||||
|
||||
|
||||
def unpack_sam3_mask(packed_mask: torch.Tensor) -> torch.Tensor:
|
||||
"""Unpack exactly one object/frame mask, avoiding full-video expansion."""
|
||||
|
||||
if not isinstance(packed_mask, torch.Tensor):
|
||||
raise TypeError("packed_mask must be a torch.Tensor.")
|
||||
if packed_mask.dtype != torch.uint8 or packed_mask.ndim != 2:
|
||||
raise ValueError("packed_mask must be uint8 with shape [height, packed_width].")
|
||||
bits = torch.tensor(
|
||||
(1, 2, 4, 8, 16, 32, 64, 128),
|
||||
dtype=torch.uint8,
|
||||
device=packed_mask.device,
|
||||
)
|
||||
return (
|
||||
torch.bitwise_and(packed_mask.unsqueeze(-1), bits)
|
||||
.ne(0)
|
||||
.reshape(packed_mask.shape[0], packed_mask.shape[1] * 8)
|
||||
)
|
||||
|
||||
|
||||
def iter_sam3_masks(
|
||||
track_data: Mapping[str, Any],
|
||||
*,
|
||||
present_only: bool = False,
|
||||
) -> Iterator[tuple[int, int, torch.Tensor]]:
|
||||
"""Yield one unpacked mask at a time as ``(frame, object, mask)``."""
|
||||
|
||||
layout = validate_sam3_track_data(track_data)
|
||||
packed = track_data["packed_masks"]
|
||||
if packed is None:
|
||||
return
|
||||
for frame_index in range(layout.n_frames):
|
||||
for object_index in range(layout.n_objects):
|
||||
mask = unpack_sam3_mask(packed[frame_index, object_index])
|
||||
if present_only and not bool(mask.any().item()):
|
||||
continue
|
||||
yield frame_index, object_index, mask
|
||||
|
||||
|
||||
def _seeds_from_detections(
|
||||
sequence: DetectionSequence,
|
||||
) -> list[_SeedIdentity]:
|
||||
for frame in sequence.frames:
|
||||
if frame.detections:
|
||||
return [
|
||||
_SeedIdentity(
|
||||
track_id=detection.track_id,
|
||||
label=detection.label,
|
||||
text=detection.text,
|
||||
score=detection.score,
|
||||
source=detection.source,
|
||||
)
|
||||
for detection in frame.detections
|
||||
]
|
||||
return []
|
||||
|
||||
|
||||
def _seeds_from_tracks(sequence: TrackSequence) -> list[_SeedIdentity]:
|
||||
return [
|
||||
_SeedIdentity(
|
||||
track_id=track.track_id,
|
||||
label=track.label or track.detections[0].label,
|
||||
text=track.detections[0].text,
|
||||
score=track.score,
|
||||
source=track.source,
|
||||
)
|
||||
for track in sequence.tracks
|
||||
]
|
||||
|
||||
|
||||
def _seed_identities(
|
||||
*,
|
||||
seed_detections: DetectionSequence | None,
|
||||
seed_tracks: TrackSequence | None,
|
||||
n_objects: int,
|
||||
) -> tuple[tuple[_SeedIdentity, ...], int]:
|
||||
if seed_detections is not None and seed_tracks is not None:
|
||||
raise ValueError("Connect seed_detections or seed_tracks, not both.")
|
||||
if seed_detections is not None:
|
||||
if not isinstance(seed_detections, DetectionSequence):
|
||||
raise TypeError("seed_detections must be a DetectionSequence.")
|
||||
seeds = _seeds_from_detections(seed_detections)
|
||||
elif seed_tracks is not None:
|
||||
if not isinstance(seed_tracks, TrackSequence):
|
||||
raise TypeError("seed_tracks must be a TrackSequence.")
|
||||
seeds = _seeds_from_tracks(seed_tracks)
|
||||
else:
|
||||
seeds = []
|
||||
|
||||
used_ids: set[int] = set()
|
||||
next_id = 0
|
||||
identities = []
|
||||
for object_index in range(n_objects):
|
||||
seed = seeds[object_index] if object_index < len(seeds) else None
|
||||
preferred = None if seed is None else seed.track_id
|
||||
if preferred is not None and preferred not in used_ids:
|
||||
track_id = preferred
|
||||
else:
|
||||
while next_id in used_ids:
|
||||
next_id += 1
|
||||
track_id = next_id
|
||||
next_id += 1
|
||||
used_ids.add(track_id)
|
||||
identities.append(
|
||||
_SeedIdentity(
|
||||
track_id=track_id,
|
||||
label=None if seed is None else seed.label,
|
||||
text=None if seed is None else seed.text,
|
||||
score=None if seed is None else seed.score,
|
||||
source=None if seed is None else seed.source,
|
||||
)
|
||||
)
|
||||
return tuple(identities), min(len(seeds), n_objects)
|
||||
|
||||
|
||||
def _scaled_bbox(
|
||||
bbox: tuple[float, float, float, float],
|
||||
layout: SAM3TrackLayout,
|
||||
) -> tuple[float, float, float, float]:
|
||||
scale_x = layout.orig_width / layout.mask_width
|
||||
scale_y = layout.orig_height / layout.mask_height
|
||||
x1, y1, x2, y2 = bbox
|
||||
return clip_box(
|
||||
(
|
||||
x1 * scale_x,
|
||||
y1 * scale_y,
|
||||
x2 * scale_x,
|
||||
y2 * scale_y,
|
||||
),
|
||||
layout.orig_width,
|
||||
layout.orig_height,
|
||||
)
|
||||
|
||||
|
||||
def sam3_track_data_to_tracks(
|
||||
track_data: Mapping[str, Any],
|
||||
*,
|
||||
seed_detections: DetectionSequence | None = None,
|
||||
seed_tracks: TrackSequence | None = None,
|
||||
fps: float | None = None,
|
||||
source: str = SAM3_ADAPTER_SOURCE,
|
||||
) -> TrackSequence:
|
||||
"""Create canonical sparse metadata while retaining packed masks separately."""
|
||||
|
||||
layout = validate_sam3_track_data(track_data)
|
||||
if fps is not None:
|
||||
fps = float(fps)
|
||||
if not math.isfinite(fps) or fps <= 0:
|
||||
raise ValueError("fps must be finite and positive or None.")
|
||||
identities, seed_count = _seed_identities(
|
||||
seed_detections=seed_detections,
|
||||
seed_tracks=seed_tracks,
|
||||
n_objects=layout.n_objects,
|
||||
)
|
||||
detections_by_object: list[list[Detection]] = [
|
||||
[] for _index in range(layout.n_objects)
|
||||
]
|
||||
|
||||
for frame_index, object_index, mask in iter_sam3_masks(
|
||||
track_data, present_only=True
|
||||
):
|
||||
bbox = bbox_from_mask(mask)
|
||||
if bbox is None:
|
||||
continue
|
||||
identity = identities[object_index]
|
||||
timestamp = frame_index / fps if fps is not None else 0.0
|
||||
score = layout.scores[object_index]
|
||||
if score is None:
|
||||
score = identity.score
|
||||
detections_by_object[object_index].append(
|
||||
Detection(
|
||||
bbox_xyxy=_scaled_bbox(bbox, layout),
|
||||
label=identity.label,
|
||||
text=identity.text,
|
||||
score=score,
|
||||
frame_index=frame_index,
|
||||
timestamp=timestamp,
|
||||
track_id=identity.track_id,
|
||||
source=source,
|
||||
metadata={
|
||||
"observation": "propagated",
|
||||
"visibility": "visible",
|
||||
"sam3_object_index": object_index,
|
||||
"mask_ref": {
|
||||
"type": SAM3_TRACK_DATA,
|
||||
"frame_index": frame_index,
|
||||
"object_index": object_index,
|
||||
},
|
||||
},
|
||||
)
|
||||
)
|
||||
|
||||
tracks = []
|
||||
for object_index, detections in enumerate(detections_by_object):
|
||||
if not detections:
|
||||
continue
|
||||
identity = identities[object_index]
|
||||
present_frames = len(detections)
|
||||
final_state = (
|
||||
"active" if detections[-1].frame_index == layout.n_frames - 1 else "lost"
|
||||
)
|
||||
score = layout.scores[object_index]
|
||||
if score is None:
|
||||
score = identity.score
|
||||
tracks.append(
|
||||
Track(
|
||||
track_id=identity.track_id,
|
||||
detections=tuple(detections),
|
||||
label=identity.label,
|
||||
score=score,
|
||||
source=source,
|
||||
metadata={
|
||||
"state": final_state,
|
||||
"sam3_object_index": object_index,
|
||||
"first_frame": detections[0].frame_index,
|
||||
"last_observed_frame": detections[-1].frame_index,
|
||||
"present_frames": present_frames,
|
||||
"presence_ratio": (
|
||||
present_frames / layout.n_frames if layout.n_frames else 0.0
|
||||
),
|
||||
"seeded": object_index < seed_count,
|
||||
},
|
||||
)
|
||||
)
|
||||
return TrackSequence(
|
||||
width=layout.orig_width,
|
||||
height=layout.orig_height,
|
||||
tracks=tuple(sorted(tracks, key=lambda item: item.track_id)),
|
||||
frame_count=layout.n_frames,
|
||||
fps=fps,
|
||||
source=source,
|
||||
metadata={
|
||||
"adapter": "sam3-track-data/v1",
|
||||
"mask_payload": {
|
||||
"type": SAM3_TRACK_DATA,
|
||||
"encoding": "little-endian-bitpack",
|
||||
"mask_width": layout.mask_width,
|
||||
"mask_height": layout.mask_height,
|
||||
},
|
||||
"object_slots": layout.n_objects,
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
def track_report_payload(tracks: TrackSequence) -> dict[str, Any]:
|
||||
"""Return a compact, history-safe report with no tensor content."""
|
||||
|
||||
if not isinstance(tracks, TrackSequence):
|
||||
raise TypeError("tracks must be a TrackSequence.")
|
||||
records = []
|
||||
state_counts: dict[str, int] = {}
|
||||
total_observations = 0
|
||||
for track in tracks.tracks:
|
||||
observations: dict[str, int] = {}
|
||||
for detection in track.detections:
|
||||
kind = str(detection.metadata.to_dict().get("observation", "detected"))
|
||||
observations[kind] = observations.get(kind, 0) + 1
|
||||
total_observations += len(track.detections)
|
||||
state = str(track.metadata.to_dict().get("state", "unknown"))
|
||||
state_counts[state] = state_counts.get(state, 0) + 1
|
||||
records.append(
|
||||
{
|
||||
"track_id": track.track_id,
|
||||
"label": track.label,
|
||||
"state": state,
|
||||
"score": track.score,
|
||||
"first_frame": track.detections[0].frame_index,
|
||||
"last_frame": track.detections[-1].frame_index,
|
||||
"observation_count": len(track.detections),
|
||||
"observations": observations,
|
||||
}
|
||||
)
|
||||
media: dict[str, Any] = {
|
||||
"width": tracks.width,
|
||||
"height": tracks.height,
|
||||
"frame_count": tracks.frame_count,
|
||||
}
|
||||
if tracks.fps is not None:
|
||||
media["fps"] = tracks.fps
|
||||
return {
|
||||
"schema": "comfyui-vlm/track-report",
|
||||
"version": 1,
|
||||
"media": media,
|
||||
"track_count": len(tracks.tracks),
|
||||
"observation_count": total_observations,
|
||||
"state_counts": dict(sorted(state_counts.items())),
|
||||
"tracks": records,
|
||||
}
|
||||
|
||||
|
||||
def track_report_json(
|
||||
tracks: TrackSequence,
|
||||
*,
|
||||
indent: int | None = 2,
|
||||
) -> str:
|
||||
return json.dumps(
|
||||
track_report_payload(tracks),
|
||||
ensure_ascii=False,
|
||||
allow_nan=False,
|
||||
sort_keys=True,
|
||||
indent=indent,
|
||||
)
|
||||
|
||||
|
||||
def track_report_text(tracks: TrackSequence) -> str:
|
||||
report = track_report_payload(tracks)
|
||||
media = report["media"]
|
||||
lines = [
|
||||
(
|
||||
f"Tracks: {report['track_count']} | "
|
||||
f"Observations: {report['observation_count']} | "
|
||||
f"Frames: {media['frame_count']} | "
|
||||
f"Size: {media['width']}x{media['height']}"
|
||||
)
|
||||
]
|
||||
if "fps" in media:
|
||||
lines[0] += f" | FPS: {media['fps']:g}"
|
||||
for track in report["tracks"]:
|
||||
label = track["label"] or "(unlabeled)"
|
||||
lines.append(
|
||||
f"#{track['track_id']} {label}: {track['state']}, "
|
||||
f"frames {track['first_frame']}-{track['last_frame']}, "
|
||||
f"{track['observation_count']} observations"
|
||||
)
|
||||
return "\n".join(lines)
|
||||
|
||||
|
||||
class VLMSAM3TrackAdapter:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"track_data": (SAM3_TRACK_DATA,),
|
||||
"fps": (
|
||||
"FLOAT",
|
||||
{
|
||||
"default": 0.0,
|
||||
"min": 0.0,
|
||||
"max": 1000.0,
|
||||
"step": 0.01,
|
||||
"tooltip": "0 keeps timestamps unknown.",
|
||||
},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"seed_detections": (VLM_DETECTIONS,),
|
||||
"seed_tracks": (VLM_TRACKS,),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = (VLM_TRACKS, SAM3_TRACK_DATA)
|
||||
RETURN_NAMES = ("tracks", "track_data")
|
||||
FUNCTION = "adapt"
|
||||
CATEGORY = "VLM Nodes/Vision/Tracking"
|
||||
|
||||
def adapt(
|
||||
self,
|
||||
track_data,
|
||||
fps,
|
||||
seed_detections=None,
|
||||
seed_tracks=None,
|
||||
):
|
||||
tracks = sam3_track_data_to_tracks(
|
||||
track_data,
|
||||
seed_detections=seed_detections,
|
||||
seed_tracks=seed_tracks,
|
||||
fps=None if fps <= 0 else fps,
|
||||
)
|
||||
return tracks, track_data
|
||||
|
||||
|
||||
class VLMTrackReport:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {"required": {"tracks": (VLM_TRACKS,)}}
|
||||
|
||||
RETURN_TYPES = ("STRING", "STRING")
|
||||
RETURN_NAMES = ("report_json", "report_text")
|
||||
FUNCTION = "report"
|
||||
CATEGORY = "VLM Nodes/Vision/Tracking"
|
||||
OUTPUT_NODE = True
|
||||
|
||||
def report(self, tracks):
|
||||
report_json = track_report_json(tracks)
|
||||
report_text = track_report_text(tracks)
|
||||
return {
|
||||
"ui": {"text": [report_text]},
|
||||
"result": (report_json, report_text),
|
||||
}
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"VLMSAM3TrackAdapter": VLMSAM3TrackAdapter,
|
||||
"VLMTrackReport": VLMTrackReport,
|
||||
}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"VLMSAM3TrackAdapter": "VLM SAM3 Track Adapter",
|
||||
"VLMTrackReport": "VLM Track Report",
|
||||
}
|
||||
|
||||
__all__ = [
|
||||
"NODE_CLASS_MAPPINGS",
|
||||
"NODE_DISPLAY_NAME_MAPPINGS",
|
||||
"SAM3TrackLayout",
|
||||
"SAM3_ADAPTER_SOURCE",
|
||||
"SAM3_TRACK_DATA",
|
||||
"VLMSAM3TrackAdapter",
|
||||
"VLMTrackReport",
|
||||
"iter_sam3_masks",
|
||||
"sam3_track_data_to_tracks",
|
||||
"track_report_json",
|
||||
"track_report_payload",
|
||||
"track_report_text",
|
||||
"unpack_sam3_mask",
|
||||
"validate_sam3_track_data",
|
||||
]
|
||||
+1075
-101
File diff suppressed because it is too large
Load Diff
File diff suppressed because it is too large
Load Diff
+907
-258
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,766 @@
|
||||
"""Deterministic tracking-by-detection for canonical VLM vision payloads.
|
||||
|
||||
The tracker intentionally owns only temporal association and identity. Dense
|
||||
mask propagation remains the responsibility of SAM-style video models. This
|
||||
keeps the baseline portable across CUDA, ROCm, MPS, XPU, and CPU systems.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import math
|
||||
from dataclasses import dataclass, field
|
||||
from typing import Iterable
|
||||
|
||||
import numpy as np
|
||||
from scipy.optimize import linear_sum_assignment
|
||||
|
||||
from .geometry import bbox_iou, clip_box, mask_iou
|
||||
from .vision_types import (
|
||||
VLM_DETECTIONS,
|
||||
VLM_TRACKS,
|
||||
Detection,
|
||||
DetectionSequence,
|
||||
FrozenDict,
|
||||
Track,
|
||||
TrackSequence,
|
||||
)
|
||||
|
||||
TRACKER_SOURCE = "vlm-bytetrack"
|
||||
_CHI_SQUARE_FOUR_DOF_99 = 13.2767
|
||||
_MIN_SIZE = 1.0e-3
|
||||
|
||||
|
||||
def _normalized_label(value: str | None) -> str | None:
|
||||
if value is None:
|
||||
return None
|
||||
normalized = " ".join(value.casefold().split())
|
||||
return normalized or None
|
||||
|
||||
|
||||
def _score_or_one(detection: Detection) -> float:
|
||||
return 1.0 if detection.score is None else detection.score
|
||||
|
||||
|
||||
def _box_to_measurement(box: Iterable[float]) -> np.ndarray:
|
||||
x1, y1, x2, y2 = (float(value) for value in box)
|
||||
return np.asarray(
|
||||
(
|
||||
(x1 + x2) * 0.5,
|
||||
(y1 + y2) * 0.5,
|
||||
max(x2 - x1, _MIN_SIZE),
|
||||
max(y2 - y1, _MIN_SIZE),
|
||||
),
|
||||
dtype=np.float64,
|
||||
)
|
||||
|
||||
|
||||
def _measurement_to_box(measurement: np.ndarray) -> tuple[float, ...]:
|
||||
center_x, center_y, width, height = measurement[:4]
|
||||
width = max(float(width), _MIN_SIZE)
|
||||
height = max(float(height), _MIN_SIZE)
|
||||
return (
|
||||
float(center_x - width * 0.5),
|
||||
float(center_y - height * 0.5),
|
||||
float(center_x + width * 0.5),
|
||||
float(center_y + height * 0.5),
|
||||
)
|
||||
|
||||
|
||||
class _BoxKalmanFilter:
|
||||
"""Small constant-velocity Kalman filter with no optional dependencies."""
|
||||
|
||||
_observation = np.concatenate(
|
||||
(np.eye(4, dtype=np.float64), np.zeros((4, 4), dtype=np.float64)),
|
||||
axis=1,
|
||||
)
|
||||
|
||||
def __init__(self, box: Iterable[float]):
|
||||
measurement = _box_to_measurement(box)
|
||||
self.mean = np.concatenate((measurement, np.zeros(4, dtype=np.float64)))
|
||||
scale = max(measurement[2], measurement[3], 1.0)
|
||||
self.covariance = np.diag(
|
||||
(
|
||||
scale * scale * 0.01,
|
||||
scale * scale * 0.01,
|
||||
scale * scale * 0.04,
|
||||
scale * scale * 0.04,
|
||||
scale * scale,
|
||||
scale * scale,
|
||||
scale * scale * 0.25,
|
||||
scale * scale * 0.25,
|
||||
)
|
||||
)
|
||||
|
||||
@property
|
||||
def box(self) -> tuple[float, ...]:
|
||||
return _measurement_to_box(self.mean)
|
||||
|
||||
def predict(self, delta_seconds: float) -> None:
|
||||
delta = max(float(delta_seconds), 1.0e-6)
|
||||
transition = np.eye(8, dtype=np.float64)
|
||||
transition[:4, 4:] = np.eye(4, dtype=np.float64) * delta
|
||||
scale = max(self.mean[2], self.mean[3], 1.0)
|
||||
position_noise = max(scale * 0.02 * delta, 1.0e-3)
|
||||
velocity_noise = max(scale * 0.01 * math.sqrt(delta), 1.0e-3)
|
||||
process_noise = np.diag((position_noise,) * 4 + (velocity_noise,) * 4) ** 2
|
||||
self.mean = transition @ self.mean
|
||||
self.covariance = transition @ self.covariance @ transition.T + process_noise
|
||||
self.mean[2:4] = np.maximum(self.mean[2:4], _MIN_SIZE)
|
||||
|
||||
def projected(self) -> tuple[np.ndarray, np.ndarray]:
|
||||
scale = max(self.mean[2], self.mean[3], 1.0)
|
||||
measurement_noise = (
|
||||
np.diag(
|
||||
(
|
||||
max(scale * 0.025, 1.0e-3),
|
||||
max(scale * 0.025, 1.0e-3),
|
||||
max(scale * 0.05, 1.0e-3),
|
||||
max(scale * 0.05, 1.0e-3),
|
||||
)
|
||||
)
|
||||
** 2
|
||||
)
|
||||
projected_mean = self._observation @ self.mean
|
||||
projected_covariance = (
|
||||
self._observation @ self.covariance @ self._observation.T
|
||||
+ measurement_noise
|
||||
)
|
||||
return projected_mean, projected_covariance
|
||||
|
||||
def gating_distance(self, box: Iterable[float]) -> float:
|
||||
measurement = _box_to_measurement(box)
|
||||
projected_mean, projected_covariance = self.projected()
|
||||
residual = measurement - projected_mean
|
||||
try:
|
||||
solved = np.linalg.solve(projected_covariance, residual)
|
||||
except np.linalg.LinAlgError:
|
||||
solved = np.linalg.pinv(projected_covariance) @ residual
|
||||
return float(residual @ solved)
|
||||
|
||||
def update(self, box: Iterable[float]) -> None:
|
||||
measurement = _box_to_measurement(box)
|
||||
projected_mean, projected_covariance = self.projected()
|
||||
cross_covariance = self.covariance @ self._observation.T
|
||||
try:
|
||||
gain = np.linalg.solve(projected_covariance, cross_covariance.T).T
|
||||
except np.linalg.LinAlgError:
|
||||
gain = cross_covariance @ np.linalg.pinv(projected_covariance)
|
||||
innovation = measurement - projected_mean
|
||||
self.mean = self.mean + gain @ innovation
|
||||
identity = np.eye(8, dtype=np.float64)
|
||||
residual_projection = identity - gain @ self._observation
|
||||
self.covariance = residual_projection @ self.covariance @ residual_projection.T
|
||||
self.mean[2:4] = np.maximum(self.mean[2:4], _MIN_SIZE)
|
||||
|
||||
|
||||
def _merged_metadata(
|
||||
detection: Detection,
|
||||
*,
|
||||
observation: str,
|
||||
track_state: str,
|
||||
association_stage: str,
|
||||
association_score: float | None,
|
||||
) -> FrozenDict:
|
||||
metadata = detection.metadata.to_dict()
|
||||
if detection.track_id is not None:
|
||||
metadata.setdefault("source_track_id", detection.track_id)
|
||||
metadata.update(
|
||||
{
|
||||
"observation": observation,
|
||||
"track_state": track_state,
|
||||
"association_stage": association_stage,
|
||||
"association_score": association_score,
|
||||
}
|
||||
)
|
||||
return FrozenDict(metadata)
|
||||
|
||||
|
||||
def _tracked_detection(
|
||||
detection: Detection,
|
||||
*,
|
||||
track_id: int,
|
||||
timestamp: float,
|
||||
track_state: str,
|
||||
association_stage: str,
|
||||
association_score: float | None,
|
||||
) -> Detection:
|
||||
return Detection(
|
||||
bbox_xyxy=detection.bbox_xyxy,
|
||||
label=detection.label,
|
||||
text=detection.text,
|
||||
score=detection.score,
|
||||
polygon=detection.polygon,
|
||||
quad=detection.quad,
|
||||
frame_index=detection.frame_index,
|
||||
timestamp=timestamp,
|
||||
track_id=track_id,
|
||||
source=detection.source,
|
||||
metadata=_merged_metadata(
|
||||
detection,
|
||||
observation="detected",
|
||||
track_state=track_state,
|
||||
association_stage=association_stage,
|
||||
association_score=association_score,
|
||||
),
|
||||
mask=detection.mask,
|
||||
)
|
||||
|
||||
|
||||
@dataclass(slots=True)
|
||||
class _TrackState:
|
||||
track_id: int
|
||||
filter: _BoxKalmanFilter
|
||||
detections: list[Detection]
|
||||
label: str | None
|
||||
text: str | None
|
||||
state: str
|
||||
hits: int
|
||||
first_frame: int
|
||||
last_observed_frame: int
|
||||
last_observed_timestamp: float
|
||||
last_timestamp: float
|
||||
last_mask: object | None = None
|
||||
misses: int = 0
|
||||
removed_frame: int | None = None
|
||||
observed_scores: list[float] = field(default_factory=list)
|
||||
|
||||
@property
|
||||
def predicted_box(self) -> tuple[float, ...]:
|
||||
return self.filter.box
|
||||
|
||||
|
||||
def _labels_compatible(
|
||||
track: _TrackState,
|
||||
detection: Detection,
|
||||
*,
|
||||
label_aware: bool,
|
||||
) -> bool:
|
||||
if not label_aware:
|
||||
return True
|
||||
old_label = _normalized_label(track.label)
|
||||
new_label = _normalized_label(detection.label)
|
||||
return old_label is None or new_label is None or old_label == new_label
|
||||
|
||||
|
||||
def _overlap(track: _TrackState, detection: Detection) -> float:
|
||||
overlap = bbox_iou(track.predicted_box, detection.bbox_xyxy)
|
||||
if track.last_mask is not None and detection.mask is not None:
|
||||
try:
|
||||
overlap = max(
|
||||
overlap,
|
||||
mask_iou(track.last_mask, detection.mask),
|
||||
)
|
||||
except (TypeError, ValueError):
|
||||
# Boxes remain a valid association primitive when mask resolutions
|
||||
# differ across detector backends.
|
||||
pass
|
||||
return overlap
|
||||
|
||||
|
||||
def _hungarian_matches(
|
||||
tracks: list[_TrackState],
|
||||
detections: list[Detection],
|
||||
*,
|
||||
minimum_iou: float,
|
||||
label_aware: bool,
|
||||
motion_gate: float,
|
||||
) -> tuple[
|
||||
list[tuple[int, int, float]],
|
||||
list[int],
|
||||
list[int],
|
||||
]:
|
||||
if not tracks or not detections:
|
||||
return (
|
||||
[],
|
||||
list(range(len(tracks))),
|
||||
list(range(len(detections))),
|
||||
)
|
||||
|
||||
cost = np.full((len(tracks), len(detections)), np.inf, dtype=np.float64)
|
||||
overlaps = np.zeros_like(cost)
|
||||
for track_index, track in enumerate(tracks):
|
||||
for detection_index, detection in enumerate(detections):
|
||||
if not _labels_compatible(track, detection, label_aware=label_aware):
|
||||
continue
|
||||
if track.filter.gating_distance(detection.bbox_xyxy) > motion_gate:
|
||||
continue
|
||||
overlap = _overlap(track, detection)
|
||||
if overlap < minimum_iou:
|
||||
continue
|
||||
overlaps[track_index, detection_index] = overlap
|
||||
cost[track_index, detection_index] = 1.0 - overlap
|
||||
|
||||
finite = np.isfinite(cost)
|
||||
if not finite.any():
|
||||
return (
|
||||
[],
|
||||
list(range(len(tracks))),
|
||||
list(range(len(detections))),
|
||||
)
|
||||
safe_cost = np.where(finite, cost, 1.0e6)
|
||||
row_indices, column_indices = linear_sum_assignment(safe_cost)
|
||||
matches = sorted(
|
||||
(
|
||||
(int(row), int(column), float(overlaps[row, column]))
|
||||
for row, column in zip(row_indices, column_indices)
|
||||
if finite[row, column]
|
||||
),
|
||||
key=lambda item: (tracks[item[0]].track_id, item[1]),
|
||||
)
|
||||
matched_tracks = {track_index for track_index, _index, _score in matches}
|
||||
matched_detections = {
|
||||
detection_index for _index, detection_index, _score in matches
|
||||
}
|
||||
return (
|
||||
matches,
|
||||
[index for index in range(len(tracks)) if index not in matched_tracks],
|
||||
[index for index in range(len(detections)) if index not in matched_detections],
|
||||
)
|
||||
|
||||
|
||||
class VLMByteTracker:
|
||||
"""ByteTrack-style high/low confidence association over a whole sequence."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
*,
|
||||
high_threshold: float = 0.6,
|
||||
low_threshold: float = 0.1,
|
||||
match_iou_threshold: float = 0.3,
|
||||
low_match_iou_threshold: float = 0.2,
|
||||
max_age_seconds: float = 1.0,
|
||||
min_hits: int = 2,
|
||||
label_aware: bool = True,
|
||||
emit_predictions: bool = True,
|
||||
motion_gate: float = _CHI_SQUARE_FOUR_DOF_99,
|
||||
fps_fallback: float = 30.0,
|
||||
):
|
||||
values = (
|
||||
high_threshold,
|
||||
low_threshold,
|
||||
match_iou_threshold,
|
||||
low_match_iou_threshold,
|
||||
)
|
||||
if any(not 0.0 <= float(value) <= 1.0 for value in values):
|
||||
raise ValueError("Thresholds must be between 0 and 1.")
|
||||
if low_threshold > high_threshold:
|
||||
raise ValueError(
|
||||
"low_threshold must be less than or equal to high_threshold."
|
||||
)
|
||||
if not math.isfinite(float(max_age_seconds)) or max_age_seconds < 0:
|
||||
raise ValueError("max_age_seconds must be finite and non-negative.")
|
||||
if not isinstance(min_hits, int) or min_hits < 1:
|
||||
raise ValueError("min_hits must be a positive integer.")
|
||||
if not math.isfinite(float(motion_gate)) or motion_gate <= 0:
|
||||
raise ValueError("motion_gate must be finite and positive.")
|
||||
if not math.isfinite(float(fps_fallback)) or fps_fallback <= 0:
|
||||
raise ValueError("fps_fallback must be finite and positive.")
|
||||
self.high_threshold = float(high_threshold)
|
||||
self.low_threshold = float(low_threshold)
|
||||
self.match_iou_threshold = float(match_iou_threshold)
|
||||
self.low_match_iou_threshold = float(low_match_iou_threshold)
|
||||
self.max_age_seconds = float(max_age_seconds)
|
||||
self.min_hits = min_hits
|
||||
self.label_aware = bool(label_aware)
|
||||
self.emit_predictions = bool(emit_predictions)
|
||||
self.motion_gate = float(motion_gate)
|
||||
self.fps_fallback = float(fps_fallback)
|
||||
self._tracks: list[_TrackState] = []
|
||||
self._next_track_id = 0
|
||||
|
||||
def _timestamp(
|
||||
self,
|
||||
frame_index: int,
|
||||
frame_timestamp: float | None,
|
||||
fps: float,
|
||||
) -> float:
|
||||
expected = frame_index / fps
|
||||
if frame_timestamp is None or (frame_index > 0 and frame_timestamp <= 0.0):
|
||||
return expected
|
||||
return max(float(frame_timestamp), expected)
|
||||
|
||||
def _spawn(
|
||||
self,
|
||||
detection: Detection,
|
||||
*,
|
||||
timestamp: float,
|
||||
) -> None:
|
||||
state = "active" if self.min_hits == 1 else "tentative"
|
||||
track_id = self._next_track_id
|
||||
self._next_track_id += 1
|
||||
tracked = _tracked_detection(
|
||||
detection,
|
||||
track_id=track_id,
|
||||
timestamp=timestamp,
|
||||
track_state=state,
|
||||
association_stage="new",
|
||||
association_score=None,
|
||||
)
|
||||
scores = [] if detection.score is None else [detection.score]
|
||||
self._tracks.append(
|
||||
_TrackState(
|
||||
track_id=track_id,
|
||||
filter=_BoxKalmanFilter(detection.bbox_xyxy),
|
||||
detections=[tracked],
|
||||
label=detection.label,
|
||||
text=detection.text,
|
||||
state=state,
|
||||
hits=1,
|
||||
first_frame=detection.frame_index,
|
||||
last_observed_frame=detection.frame_index,
|
||||
last_observed_timestamp=timestamp,
|
||||
last_timestamp=timestamp,
|
||||
last_mask=detection.mask,
|
||||
observed_scores=scores,
|
||||
)
|
||||
)
|
||||
|
||||
def _update_track(
|
||||
self,
|
||||
track: _TrackState,
|
||||
detection: Detection,
|
||||
*,
|
||||
timestamp: float,
|
||||
stage: str,
|
||||
association_score: float,
|
||||
) -> None:
|
||||
track.filter.update(detection.bbox_xyxy)
|
||||
track.hits += 1
|
||||
track.misses = 0
|
||||
track.state = "active" if track.hits >= self.min_hits else "tentative"
|
||||
if track.label is None:
|
||||
track.label = detection.label
|
||||
if track.text is None:
|
||||
track.text = detection.text
|
||||
track.last_observed_frame = detection.frame_index
|
||||
track.last_observed_timestamp = timestamp
|
||||
track.last_timestamp = timestamp
|
||||
track.last_mask = detection.mask
|
||||
if detection.score is not None:
|
||||
track.observed_scores.append(detection.score)
|
||||
track.detections.append(
|
||||
_tracked_detection(
|
||||
detection,
|
||||
track_id=track.track_id,
|
||||
timestamp=timestamp,
|
||||
track_state=track.state,
|
||||
association_stage=stage,
|
||||
association_score=association_score,
|
||||
)
|
||||
)
|
||||
|
||||
def _mark_missed(
|
||||
self,
|
||||
track: _TrackState,
|
||||
*,
|
||||
frame_index: int,
|
||||
timestamp: float,
|
||||
width: int,
|
||||
height: int,
|
||||
) -> None:
|
||||
track.misses += 1
|
||||
elapsed = max(0.0, timestamp - track.last_observed_timestamp)
|
||||
if track.state == "tentative" or elapsed > self.max_age_seconds:
|
||||
track.state = "removed"
|
||||
track.removed_frame = frame_index
|
||||
return
|
||||
track.state = "lost"
|
||||
if not self.emit_predictions:
|
||||
return
|
||||
box = clip_box(track.predicted_box, width, height)
|
||||
if box[2] <= box[0] or box[3] <= box[1]:
|
||||
return
|
||||
track.detections.append(
|
||||
Detection(
|
||||
bbox_xyxy=box,
|
||||
label=track.label,
|
||||
text=track.text,
|
||||
score=None,
|
||||
frame_index=frame_index,
|
||||
timestamp=timestamp,
|
||||
track_id=track.track_id,
|
||||
source=TRACKER_SOURCE,
|
||||
metadata={
|
||||
"observation": "predicted",
|
||||
"track_state": "lost",
|
||||
"association_stage": "unmatched",
|
||||
"association_score": None,
|
||||
},
|
||||
)
|
||||
)
|
||||
|
||||
def _predict(
|
||||
self,
|
||||
*,
|
||||
timestamp: float,
|
||||
) -> list[_TrackState]:
|
||||
candidates = [track for track in self._tracks if track.state != "removed"]
|
||||
for track in candidates:
|
||||
delta = max(timestamp - track.last_timestamp, 1.0e-6)
|
||||
track.filter.predict(delta)
|
||||
track.last_timestamp = timestamp
|
||||
return candidates
|
||||
|
||||
def _process_frame(
|
||||
self,
|
||||
detections: list[Detection],
|
||||
*,
|
||||
frame_index: int,
|
||||
timestamp: float,
|
||||
width: int,
|
||||
height: int,
|
||||
) -> None:
|
||||
candidates = self._predict(timestamp=timestamp)
|
||||
high = [
|
||||
detection
|
||||
for detection in detections
|
||||
if _score_or_one(detection) >= self.high_threshold
|
||||
]
|
||||
low = [
|
||||
detection
|
||||
for detection in detections
|
||||
if self.low_threshold <= _score_or_one(detection) < self.high_threshold
|
||||
]
|
||||
|
||||
high_matches, unmatched_candidate_indices, unmatched_high_indices = (
|
||||
_hungarian_matches(
|
||||
candidates,
|
||||
high,
|
||||
minimum_iou=self.match_iou_threshold,
|
||||
label_aware=self.label_aware,
|
||||
motion_gate=self.motion_gate,
|
||||
)
|
||||
)
|
||||
matched_track_ids = set()
|
||||
for track_index, detection_index, overlap in high_matches:
|
||||
track = candidates[track_index]
|
||||
self._update_track(
|
||||
track,
|
||||
high[detection_index],
|
||||
timestamp=timestamp,
|
||||
stage="high",
|
||||
association_score=overlap,
|
||||
)
|
||||
matched_track_ids.add(track.track_id)
|
||||
|
||||
low_candidates = [
|
||||
candidates[index]
|
||||
for index in unmatched_candidate_indices
|
||||
if candidates[index].state in {"active", "lost"}
|
||||
]
|
||||
low_matches, _unmatched_low_track_indices, _unmatched_low_indices = (
|
||||
_hungarian_matches(
|
||||
low_candidates,
|
||||
low,
|
||||
minimum_iou=self.low_match_iou_threshold,
|
||||
label_aware=self.label_aware,
|
||||
motion_gate=self.motion_gate,
|
||||
)
|
||||
)
|
||||
for track_index, detection_index, overlap in low_matches:
|
||||
track = low_candidates[track_index]
|
||||
self._update_track(
|
||||
track,
|
||||
low[detection_index],
|
||||
timestamp=timestamp,
|
||||
stage="low",
|
||||
association_score=overlap,
|
||||
)
|
||||
matched_track_ids.add(track.track_id)
|
||||
|
||||
for track in candidates:
|
||||
if track.track_id not in matched_track_ids:
|
||||
self._mark_missed(
|
||||
track,
|
||||
frame_index=frame_index,
|
||||
timestamp=timestamp,
|
||||
width=width,
|
||||
height=height,
|
||||
)
|
||||
|
||||
for detection_index in unmatched_high_indices:
|
||||
self._spawn(high[detection_index], timestamp=timestamp)
|
||||
|
||||
def track(self, sequence: DetectionSequence) -> TrackSequence:
|
||||
if not isinstance(sequence, DetectionSequence):
|
||||
raise TypeError("sequence must be a DetectionSequence.")
|
||||
self._tracks = []
|
||||
self._next_track_id = 0
|
||||
fps = sequence.fps or self.fps_fallback
|
||||
frames = {frame.frame_index: frame for frame in sequence.frames}
|
||||
for frame_index in range(sequence.frame_count):
|
||||
frame = frames.get(frame_index)
|
||||
timestamp = self._timestamp(
|
||||
frame_index,
|
||||
None if frame is None else frame.timestamp,
|
||||
fps,
|
||||
)
|
||||
detections = (
|
||||
[]
|
||||
if frame is None
|
||||
else [
|
||||
Detection(
|
||||
bbox_xyxy=detection.bbox_xyxy,
|
||||
label=detection.label,
|
||||
text=detection.text,
|
||||
score=detection.score,
|
||||
polygon=detection.polygon,
|
||||
quad=detection.quad,
|
||||
frame_index=frame_index,
|
||||
timestamp=timestamp,
|
||||
track_id=detection.track_id,
|
||||
source=detection.source,
|
||||
metadata=detection.metadata,
|
||||
mask=detection.mask,
|
||||
)
|
||||
for detection in frame.detections
|
||||
]
|
||||
)
|
||||
self._process_frame(
|
||||
detections,
|
||||
frame_index=frame_index,
|
||||
timestamp=timestamp,
|
||||
width=sequence.width,
|
||||
height=sequence.height,
|
||||
)
|
||||
|
||||
tracks = []
|
||||
for track in sorted(self._tracks, key=lambda item: item.track_id):
|
||||
score = (
|
||||
sum(track.observed_scores) / len(track.observed_scores)
|
||||
if track.observed_scores
|
||||
else None
|
||||
)
|
||||
tracks.append(
|
||||
Track(
|
||||
track_id=track.track_id,
|
||||
detections=tuple(track.detections),
|
||||
label=track.label,
|
||||
score=score,
|
||||
source=TRACKER_SOURCE,
|
||||
metadata={
|
||||
"state": track.state,
|
||||
"hits": track.hits,
|
||||
"misses": track.misses,
|
||||
"first_frame": track.first_frame,
|
||||
"last_observed_frame": track.last_observed_frame,
|
||||
"removed_frame": track.removed_frame,
|
||||
},
|
||||
)
|
||||
)
|
||||
metadata = sequence.metadata.to_dict()
|
||||
metadata["tracker"] = {
|
||||
"algorithm": "bytetrack-style-hungarian",
|
||||
"high_threshold": self.high_threshold,
|
||||
"low_threshold": self.low_threshold,
|
||||
"match_iou_threshold": self.match_iou_threshold,
|
||||
"low_match_iou_threshold": self.low_match_iou_threshold,
|
||||
"max_age_seconds": self.max_age_seconds,
|
||||
"min_hits": self.min_hits,
|
||||
"label_aware": self.label_aware,
|
||||
"emit_predictions": self.emit_predictions,
|
||||
}
|
||||
return TrackSequence(
|
||||
width=sequence.width,
|
||||
height=sequence.height,
|
||||
tracks=tuple(tracks),
|
||||
frame_count=sequence.frame_count,
|
||||
fps=sequence.fps,
|
||||
source=TRACKER_SOURCE,
|
||||
metadata=metadata,
|
||||
)
|
||||
|
||||
|
||||
def associate_detection_sequence(
|
||||
sequence: DetectionSequence,
|
||||
**tracker_options,
|
||||
) -> TrackSequence:
|
||||
"""Convenience function for callers that do not need a reusable tracker."""
|
||||
|
||||
return VLMByteTracker(**tracker_options).track(sequence)
|
||||
|
||||
|
||||
class VLMTrackDetections:
|
||||
"""ComfyUI node wrapper for deterministic tracking-by-detection."""
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"detections": (VLM_DETECTIONS,),
|
||||
"high_threshold": (
|
||||
"FLOAT",
|
||||
{"default": 0.6, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"low_threshold": (
|
||||
"FLOAT",
|
||||
{"default": 0.1, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"match_iou_threshold": (
|
||||
"FLOAT",
|
||||
{"default": 0.3, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"low_match_iou_threshold": (
|
||||
"FLOAT",
|
||||
{"default": 0.2, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"max_age_seconds": (
|
||||
"FLOAT",
|
||||
{"default": 1.0, "min": 0.0, "max": 60.0, "step": 0.05},
|
||||
),
|
||||
"min_hits": (
|
||||
"INT",
|
||||
{"default": 2, "min": 1, "max": 100},
|
||||
),
|
||||
"label_aware": ("BOOLEAN", {"default": True}),
|
||||
"emit_predictions": ("BOOLEAN", {"default": True}),
|
||||
"fps_fallback": (
|
||||
"FLOAT",
|
||||
{"default": 30.0, "min": 0.01, "max": 1000.0},
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = (VLM_TRACKS,)
|
||||
RETURN_NAMES = ("tracks",)
|
||||
FUNCTION = "track"
|
||||
CATEGORY = "VLM Nodes/Vision/Tracking"
|
||||
|
||||
def track(
|
||||
self,
|
||||
detections,
|
||||
high_threshold,
|
||||
low_threshold,
|
||||
match_iou_threshold,
|
||||
low_match_iou_threshold,
|
||||
max_age_seconds,
|
||||
min_hits,
|
||||
label_aware,
|
||||
emit_predictions,
|
||||
fps_fallback,
|
||||
):
|
||||
tracker = VLMByteTracker(
|
||||
high_threshold=high_threshold,
|
||||
low_threshold=low_threshold,
|
||||
match_iou_threshold=match_iou_threshold,
|
||||
low_match_iou_threshold=low_match_iou_threshold,
|
||||
max_age_seconds=max_age_seconds,
|
||||
min_hits=min_hits,
|
||||
label_aware=label_aware,
|
||||
emit_predictions=emit_predictions,
|
||||
fps_fallback=fps_fallback,
|
||||
)
|
||||
return (tracker.track(detections),)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"VLMTrackDetections": VLMTrackDetections}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"VLMTrackDetections": "VLM Track Detections"}
|
||||
|
||||
__all__ = [
|
||||
"NODE_CLASS_MAPPINGS",
|
||||
"NODE_DISPLAY_NAME_MAPPINGS",
|
||||
"TRACKER_SOURCE",
|
||||
"VLMByteTracker",
|
||||
"VLMTrackDetections",
|
||||
"associate_detection_sequence",
|
||||
]
|
||||
+123
@@ -0,0 +1,123 @@
|
||||
"""UForm Gen2 Qwen node with safe lazy loading."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import torch
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
inference_context,
|
||||
model_device,
|
||||
require_module,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
MODEL_ID = "unum-cloud/uform-gen2-qwen-500m"
|
||||
|
||||
|
||||
class UformGen2QwenChat:
|
||||
def __init__(self):
|
||||
transformers = require_module("transformers")
|
||||
model_path = snapshot_download(
|
||||
MODEL_ID, "uform-gen2-qwen", ignore_patterns=["*.bin"]
|
||||
)
|
||||
self.dtype = torch_dtype("float16")
|
||||
model = transformers.AutoModel.from_pretrained(
|
||||
model_path,
|
||||
trust_remote_code=True,
|
||||
torch_dtype=self.dtype,
|
||||
).eval()
|
||||
self.processor = transformers.AutoProcessor.from_pretrained(
|
||||
model_path, trust_remote_code=True
|
||||
)
|
||||
self.handle = ManagedTorchModel(model, processor=self.processor)
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
def chat(self, images, question, max_new_tokens):
|
||||
results = []
|
||||
for image in tensor_batch_to_pil(images):
|
||||
messages = [
|
||||
{"role": "system", "content": "You are a helpful assistant."},
|
||||
{"role": "user", "content": f"<image>{question}"},
|
||||
]
|
||||
input_ids = self.processor.tokenizer.apply_chat_template(
|
||||
messages,
|
||||
add_generation_prompt=True,
|
||||
return_tensors="pt",
|
||||
)
|
||||
image_tensor = self.processor.feature_extractor(image).unsqueeze(0)
|
||||
attention_mask = torch.ones(
|
||||
1,
|
||||
input_ids.shape[1] + self.processor.num_image_latents - 1,
|
||||
dtype=torch.long,
|
||||
)
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
model_inputs = {
|
||||
"input_ids": input_ids.to(device),
|
||||
"images": image_tensor.to(device),
|
||||
"attention_mask": attention_mask.to(device),
|
||||
}
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
output = model.generate(
|
||||
**model_inputs,
|
||||
max_new_tokens=int(max_new_tokens),
|
||||
eos_token_id=self.processor.tokenizer.eos_token_id,
|
||||
)
|
||||
generated = output[0, input_ids.shape[-1] :]
|
||||
results.append(
|
||||
self.processor.tokenizer.decode(
|
||||
generated, skip_special_tokens=True
|
||||
).strip()
|
||||
)
|
||||
return batch_text(results)
|
||||
|
||||
|
||||
class UformGen2QwenNode(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"question": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "Describe this image in detail.",
|
||||
},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 512, "min": 1, "max": 4096},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
FUNCTION = "uform_gen2_qwen_chat"
|
||||
CATEGORY = "VLM Nodes/Legacy/Model Loaders"
|
||||
|
||||
def uform_gen2_qwen_chat(
|
||||
self, image, question, max_new_tokens=512, unload_after=False
|
||||
):
|
||||
predictor = self.get_or_create_model(
|
||||
MODEL_ID, UformGen2QwenChat
|
||||
)
|
||||
try:
|
||||
return (predictor.chat(image, question, max_new_tokens),)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"UformGen2QwenNode": UformGen2QwenNode}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"UformGen2QwenNode": "UForm Gen2 Qwen"}
|
||||
File diff suppressed because it is too large
Load Diff
File diff suppressed because it is too large
Load Diff
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,83 @@
|
||||
[project]
|
||||
name = "comfyui_vlm_nodes"
|
||||
version = "3.3.0"
|
||||
description = "Production-ready local and API vision-language nodes for ComfyUI"
|
||||
readme = "README.md"
|
||||
requires-python = ">=3.10"
|
||||
license = "MIT"
|
||||
license-files = ["LICENSE"]
|
||||
dependencies = [
|
||||
"accelerate>=1.1,<2",
|
||||
"bitsandbytes>=0.50,<1; (sys_platform == 'linux' and platform_machine == 'x86_64') or (sys_platform == 'linux' and platform_machine == 'aarch64') or (sys_platform == 'win32' and platform_machine == 'AMD64') or (sys_platform == 'win32' and platform_machine == 'ARM64') or (sys_platform == 'darwin' and platform_machine == 'arm64')",
|
||||
"diffusers>=0.34,<1",
|
||||
"einops>=0.8,<1",
|
||||
"huggingface-hub>=1.5,<2",
|
||||
"httpx>=0.27,<1",
|
||||
"jsonschema>=4.22,<5",
|
||||
"num2words>=0.5.14,<1",
|
||||
"openai>=2,<3",
|
||||
"pydantic>=2.7,<3",
|
||||
"qwen-vl-utils>=0.0.14",
|
||||
"safetensors>=0.4.3",
|
||||
"scipy>=1.10,<2",
|
||||
"soundfile>=0.12",
|
||||
"symusic>=0.5",
|
||||
"svgelements>=1.9.6,<2",
|
||||
"transformers>=5.4,<6",
|
||||
]
|
||||
classifiers = [
|
||||
"Operating System :: Microsoft :: Windows",
|
||||
"Operating System :: POSIX :: Linux",
|
||||
"Operating System :: MacOS",
|
||||
"Environment :: GPU :: NVIDIA CUDA",
|
||||
"Environment :: GPU :: AMD ROCm",
|
||||
"Environment :: GPU :: Intel Arc",
|
||||
"Environment :: GPU :: Apple Metal",
|
||||
"Programming Language :: Python :: 3.10",
|
||||
"Programming Language :: Python :: 3.11",
|
||||
"Programming Language :: Python :: 3.12",
|
||||
"Programming Language :: Python :: 3.13",
|
||||
]
|
||||
|
||||
[project.optional-dependencies]
|
||||
quantization = [
|
||||
"accelerate>=1.1,<2",
|
||||
"bitsandbytes>=0.50,<1",
|
||||
]
|
||||
gguf = [
|
||||
"llama-cpp-python>=0.3.20,<1",
|
||||
]
|
||||
|
||||
[project.urls]
|
||||
Repository = "https://github.com/gokayfem/ComfyUI_VLM_nodes"
|
||||
Issues = "https://github.com/gokayfem/ComfyUI_VLM_nodes/issues"
|
||||
|
||||
[tool.comfy]
|
||||
PublisherId = "gokayfem"
|
||||
DisplayName = "ComfyUI VLM Nodes"
|
||||
Icon = ""
|
||||
|
||||
[tool.setuptools]
|
||||
packages = [
|
||||
"comfyui_vlm_nodes",
|
||||
"comfyui_vlm_nodes.examples",
|
||||
"comfyui_vlm_nodes.examples.vision",
|
||||
"comfyui_vlm_nodes.nodes",
|
||||
"comfyui_vlm_nodes.nodes.joytagger",
|
||||
"comfyui_vlm_nodes.web",
|
||||
"comfyui_vlm_nodes.web.js",
|
||||
]
|
||||
include-package-data = true
|
||||
|
||||
[tool.setuptools.package-dir]
|
||||
comfyui_vlm_nodes = "."
|
||||
|
||||
[tool.setuptools.package-data]
|
||||
comfyui_vlm_nodes = [
|
||||
"*.json",
|
||||
"SECURITY.md",
|
||||
"examples/*.json",
|
||||
"examples/vision/*.json",
|
||||
"requirements*.txt",
|
||||
]
|
||||
"comfyui_vlm_nodes.web.js" = ["*.js"]
|
||||
@@ -0,0 +1,4 @@
|
||||
# Optional GGUF backend. This default may build the CPU backend from source.
|
||||
# Prefer the official CUDA, Metal, ROCm/HIP, Vulkan, or SYCL wheel/build from:
|
||||
# https://github.com/abetlen/llama-cpp-python
|
||||
llama-cpp-python>=0.3.20,<1
|
||||
@@ -0,0 +1,11 @@
|
||||
# Install this file only into the isolated Moondream sidecar environment.
|
||||
# Do not install it into ComfyUI's main environment: moondream 1.3 pins
|
||||
# Pillow <11 while current ComfyUI uses a newer Pillow release.
|
||||
moondream==1.3.0
|
||||
# moondream 1.3.0 expects this exact runtime API. 0.4.7+ renamed the
|
||||
# prefix-mask kernel and is not source-compatible with kestrel 0.4.2.
|
||||
kestrel-kernels==0.4.6
|
||||
# Kestrel's CUDA 12 AOT kernels call cudaLibraryLoadData. PyTorch's cu126
|
||||
# runtime (12.6.77) does not export it; 12.9.79 does and remains within the
|
||||
# CUDA 12 ABI. Keep this inside the isolated Photon environment only.
|
||||
nvidia-cuda-runtime-cu12==12.9.79; (sys_platform == "linux" and platform_machine == "x86_64") or (sys_platform == "win32" and platform_machine == "AMD64")
|
||||
@@ -0,0 +1,5 @@
|
||||
# Optional maintained 4-bit/8-bit backend.
|
||||
# Official 0.50+ wheels cover NVIDIA CUDA, AMD ROCm, Intel XPU/CPU,
|
||||
# Apple Silicon, and supported Windows/Linux CPU architectures.
|
||||
accelerate>=1.1,<2
|
||||
bitsandbytes>=0.50,<1
|
||||
+21
-21
@@ -1,21 +1,21 @@
|
||||
openai>=0.27.8
|
||||
accelerate>=0.25.0
|
||||
huggingface-hub==0.20.1
|
||||
Pillow>=10.1.0
|
||||
transformers>=4.36.2
|
||||
torch>=2.0.1,<3.0.0
|
||||
torchvision>=0.15.2
|
||||
einops>=0.7.0
|
||||
safetensors>=0.4.1
|
||||
pillow>=9.4.0
|
||||
py-cpuinfo
|
||||
gitpython
|
||||
moviepy
|
||||
opencv-python
|
||||
scikit-build
|
||||
typing
|
||||
diskcache
|
||||
pytz
|
||||
six
|
||||
cffi
|
||||
python-dateutil>=2.7.0
|
||||
# ComfyUI provides torch, torchvision, numpy and Pillow.
|
||||
# Keep this list resolver-friendly; no package is installed during node import.
|
||||
accelerate>=1.1,<2
|
||||
# Official wheels: Linux x86_64/aarch64, Windows AMD64/ARM64, macOS arm64.
|
||||
# Unsupported machines keep every non-quantized node instead of failing install.
|
||||
bitsandbytes>=0.50,<1; (sys_platform == "linux" and platform_machine == "x86_64") or (sys_platform == "linux" and platform_machine == "aarch64") or (sys_platform == "win32" and platform_machine == "AMD64") or (sys_platform == "win32" and platform_machine == "ARM64") or (sys_platform == "darwin" and platform_machine == "arm64")
|
||||
diffusers>=0.34,<1
|
||||
einops>=0.8,<1
|
||||
huggingface-hub>=1.5,<2
|
||||
httpx>=0.27,<1
|
||||
jsonschema>=4.22,<5
|
||||
num2words>=0.5.14,<1
|
||||
openai>=2,<3
|
||||
pydantic>=2.7,<3
|
||||
qwen-vl-utils>=0.0.14
|
||||
safetensors>=0.4.3
|
||||
scipy>=1.10,<2
|
||||
soundfile>=0.12
|
||||
symusic>=0.5
|
||||
svgelements>=1.9.6,<2
|
||||
transformers>=5.4,<6
|
||||
|
||||
@@ -0,0 +1,31 @@
|
||||
"""Make the source checkout importable on every supported test runner."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import importlib.util
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
REPOSITORY = Path(__file__).resolve().parents[1]
|
||||
for candidate in (
|
||||
REPOSITORY.parent,
|
||||
REPOSITORY.parent / "ComfyUI",
|
||||
REPOSITORY.parents[1],
|
||||
):
|
||||
if candidate.exists():
|
||||
sys.path.insert(0, str(candidate))
|
||||
|
||||
# Git worktrees are often intentionally named after a feature branch rather
|
||||
# than the import package. Load this checkout explicitly so tests can never
|
||||
# pass by silently importing a sibling clone with the canonical directory name.
|
||||
if REPOSITORY.name != "ComfyUI_VLM_nodes":
|
||||
specification = importlib.util.spec_from_file_location(
|
||||
"ComfyUI_VLM_nodes",
|
||||
REPOSITORY / "__init__.py",
|
||||
submodule_search_locations=[str(REPOSITORY)],
|
||||
)
|
||||
if specification is None or specification.loader is None:
|
||||
raise RuntimeError(f"Could not load package from {REPOSITORY}.")
|
||||
package = importlib.util.module_from_spec(specification)
|
||||
sys.modules["ComfyUI_VLM_nodes"] = package
|
||||
specification.loader.exec_module(package)
|
||||
@@ -0,0 +1,46 @@
|
||||
"""Validate curated Hugging Face IDs without downloading model weights.
|
||||
|
||||
This opt-in network check resolves each repository's configuration and
|
||||
processor through the installed Transformers version. It complements, but does
|
||||
not replace, the real-weight smoke tests.
|
||||
|
||||
python tests/manual_catalog_probe.py
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
|
||||
from transformers import AutoConfig, AutoProcessor
|
||||
|
||||
from ComfyUI_VLM_nodes.nodes.modern_vlm import MODEL_CATALOG
|
||||
|
||||
|
||||
def main() -> int:
|
||||
records = []
|
||||
for label, spec in MODEL_CATALOG.items():
|
||||
if not spec.small_fast or spec.gated:
|
||||
continue
|
||||
config = AutoConfig.from_pretrained(
|
||||
spec.repo_id,
|
||||
trust_remote_code=spec.trust_remote_code,
|
||||
)
|
||||
processor = AutoProcessor.from_pretrained(
|
||||
spec.repo_id,
|
||||
trust_remote_code=spec.trust_remote_code,
|
||||
)
|
||||
records.append(
|
||||
{
|
||||
"label": label,
|
||||
"repo_id": spec.repo_id,
|
||||
"model_type": config.model_type,
|
||||
"config_class": type(config).__name__,
|
||||
"processor_class": type(processor).__name__,
|
||||
}
|
||||
)
|
||||
print("CATALOG_PROBE_JSON=" + json.dumps(records, ensure_ascii=False))
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
@@ -0,0 +1,98 @@
|
||||
"""Opt-in real-weight smoke test for the shared llama.cpp runtime.
|
||||
|
||||
The default model is a small official ggml-org Qwen checkpoint. Nothing is
|
||||
downloaded unless --download is supplied.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import time
|
||||
from pathlib import Path
|
||||
|
||||
from ComfyUI_VLM_nodes.nodes.runtime import (
|
||||
LlamaHandle,
|
||||
default_llama_threads,
|
||||
hf_download,
|
||||
llama_cpp_diagnostics,
|
||||
)
|
||||
|
||||
|
||||
def parse_args() -> argparse.Namespace:
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--model", type=Path)
|
||||
parser.add_argument("--download", action="store_true")
|
||||
parser.add_argument(
|
||||
"--repo",
|
||||
default="ggml-org/Qwen3.5-0.8B-GGUF",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--filename",
|
||||
default="Qwen3.5-0.8B-Q4_0.gguf",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--prompt",
|
||||
default="Reply with exactly: llama.cpp runtime ready",
|
||||
)
|
||||
parser.add_argument("--max-tokens", type=int, default=32)
|
||||
parser.add_argument("--n-gpu-layers", type=int, default=-1)
|
||||
return parser.parse_args()
|
||||
|
||||
|
||||
def main() -> None:
|
||||
args = parse_args()
|
||||
model_path = args.model
|
||||
if model_path is None:
|
||||
if not args.download:
|
||||
raise SystemExit(
|
||||
"Pass --model /path/to/model.gguf, or explicitly allow the "
|
||||
"small default download with --download."
|
||||
)
|
||||
model_path = hf_download(
|
||||
args.repo,
|
||||
args.filename,
|
||||
"llama-cpp-smoke",
|
||||
)
|
||||
|
||||
started = time.perf_counter()
|
||||
handle = LlamaHandle(
|
||||
model_path,
|
||||
n_ctx=2048,
|
||||
n_gpu_layers=args.n_gpu_layers,
|
||||
n_threads=default_llama_threads(),
|
||||
n_batch=512,
|
||||
n_ubatch=512,
|
||||
flash_attention="Auto",
|
||||
)
|
||||
try:
|
||||
llm = handle.ensure_loaded()
|
||||
loaded = time.perf_counter()
|
||||
response = llm.create_chat_completion(
|
||||
messages=[{"role": "user", "content": args.prompt}],
|
||||
max_tokens=args.max_tokens,
|
||||
temperature=0.0,
|
||||
seed=42,
|
||||
)
|
||||
finished = time.perf_counter()
|
||||
content = response["choices"][0]["message"]["content"]
|
||||
print(
|
||||
json.dumps(
|
||||
{
|
||||
"model": str(model_path),
|
||||
"model_bytes": model_path.stat().st_size,
|
||||
"llama_cpp": llama_cpp_diagnostics(),
|
||||
"load_seconds": round(loaded - started, 3),
|
||||
"generation_seconds": round(finished - loaded, 3),
|
||||
"response": content,
|
||||
},
|
||||
ensure_ascii=False,
|
||||
indent=2,
|
||||
)
|
||||
)
|
||||
finally:
|
||||
handle.close()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,120 @@
|
||||
"""Opt-in real-weight smoke test for the Modern VLM node.
|
||||
|
||||
This is intentionally excluded from pytest because it downloads multi-gigabyte
|
||||
models. Run one checkpoint per process so CUDA and file-handle cleanup are also
|
||||
exercised:
|
||||
|
||||
python tests/manual_model_smoke.py --model "Qwen 3.5 2B"
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import time
|
||||
|
||||
import torch
|
||||
|
||||
from ComfyUI_VLM_nodes.nodes.modern_vlm import MODEL_CATALOG, ModernVLMPredictor
|
||||
|
||||
|
||||
def test_image() -> torch.Tensor:
|
||||
image = torch.zeros((1, 96, 128, 3), dtype=torch.float32)
|
||||
image[:, 20:76, 28:104, 0] = 1.0
|
||||
return image
|
||||
|
||||
|
||||
def test_video() -> torch.Tensor:
|
||||
frames = torch.zeros((4, 96, 128, 3), dtype=torch.float32)
|
||||
for index in range(4):
|
||||
left = 12 + index * 18
|
||||
frames[index, 30:66, left : left + 24, 1] = 1.0
|
||||
return frames
|
||||
|
||||
|
||||
def main() -> int:
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--model", required=True, choices=MODEL_CATALOG)
|
||||
parser.add_argument(
|
||||
"--memory-mode",
|
||||
default="ComfyUI managed (BF16)",
|
||||
choices=[
|
||||
"ComfyUI managed (BF16)",
|
||||
"4-bit NF4 (bitsandbytes)",
|
||||
"8-bit (bitsandbytes)",
|
||||
"CPU",
|
||||
],
|
||||
)
|
||||
parser.add_argument("--video", action="store_true")
|
||||
parser.add_argument("--max-new-tokens", type=int, default=48)
|
||||
args = parser.parse_args()
|
||||
|
||||
started = time.perf_counter()
|
||||
if torch.cuda.is_available():
|
||||
torch.cuda.reset_peak_memory_stats()
|
||||
free_before, total = torch.cuda.mem_get_info()
|
||||
else:
|
||||
free_before = total = 0
|
||||
|
||||
predictor = ModernVLMPredictor(
|
||||
args.model,
|
||||
"",
|
||||
args.memory_mode,
|
||||
"Auto (SDPA)",
|
||||
)
|
||||
try:
|
||||
prompt = (
|
||||
"In this four-frame video, what color object moves horizontally? "
|
||||
"Answer with the color and shape."
|
||||
if args.video
|
||||
else (
|
||||
"Describe the dominant colors, shapes, and motion in one "
|
||||
"short factual sentence."
|
||||
)
|
||||
)
|
||||
response = predictor.generate(
|
||||
None if args.video else test_image(),
|
||||
prompt,
|
||||
"",
|
||||
args.max_new_tokens,
|
||||
0.0,
|
||||
0.9,
|
||||
test_video() if args.video else None,
|
||||
2.0,
|
||||
)
|
||||
if not response.strip():
|
||||
raise RuntimeError("The model returned an empty response.")
|
||||
if args.video and "green" not in response.lower():
|
||||
raise RuntimeError(
|
||||
f"The video frames were not understood; response was: {response}"
|
||||
)
|
||||
if not args.video and "red" not in response.lower():
|
||||
raise RuntimeError(
|
||||
f"The image was not understood; response was: {response}"
|
||||
)
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if torch.cuda.is_available():
|
||||
peak = torch.cuda.max_memory_allocated()
|
||||
free_after, _ = torch.cuda.mem_get_info()
|
||||
else:
|
||||
peak = free_after = 0
|
||||
record = {
|
||||
"model": args.model,
|
||||
"repo_id": MODEL_CATALOG[args.model].repo_id,
|
||||
"memory_mode": args.memory_mode,
|
||||
"video": args.video,
|
||||
"response": response,
|
||||
"seconds": round(time.perf_counter() - started, 2),
|
||||
"cuda_total_gib": round(total / 1024**3, 2),
|
||||
"cuda_free_before_gib": round(free_before / 1024**3, 2),
|
||||
"cuda_free_after_gib": round(free_after / 1024**3, 2),
|
||||
"cuda_peak_allocated_gib": round(peak / 1024**3, 2),
|
||||
}
|
||||
print("MODEL_SMOKE_JSON=" + json.dumps(record, ensure_ascii=False))
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
@@ -0,0 +1,294 @@
|
||||
"""Opt-in real-weight smoke tests for specialized model backends.
|
||||
|
||||
Each invocation downloads and runs one real checkpoint. Keeping one model per
|
||||
process verifies teardown and prevents one backend's CUDA state from masking
|
||||
another backend's behavior.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import time
|
||||
|
||||
import torch
|
||||
|
||||
|
||||
BACKENDS = (
|
||||
"florence-base",
|
||||
"florence-large",
|
||||
"moondream2",
|
||||
"qwen2vl-2b",
|
||||
"qwen2vl-2b-video",
|
||||
"qwen2vl-7b-4bit",
|
||||
"molmo-1b",
|
||||
"molmo-7b-d-4bit",
|
||||
"molmo-7b-o-4bit",
|
||||
"kosmos2",
|
||||
"uform",
|
||||
"mcllava",
|
||||
"joytag",
|
||||
"paligemma-caption",
|
||||
"minicpm-gguf-q4",
|
||||
"audioldm2",
|
||||
)
|
||||
|
||||
|
||||
def test_image() -> torch.Tensor:
|
||||
image = torch.zeros((1, 192, 256, 3), dtype=torch.float32)
|
||||
image[:, 48:144, 56:200, 0] = 1.0
|
||||
return image
|
||||
|
||||
|
||||
def test_video() -> torch.Tensor:
|
||||
frames = torch.zeros((4, 96, 128, 3), dtype=torch.float32)
|
||||
for index in range(4):
|
||||
left = 12 + index * 18
|
||||
frames[index, 30:66, left : left + 24, 1] = 1.0
|
||||
return frames
|
||||
|
||||
|
||||
def _run(backend: str):
|
||||
image = test_image()
|
||||
prompt = "What color is the large rectangle? Answer briefly."
|
||||
|
||||
if backend.startswith("florence-"):
|
||||
from ComfyUI_VLM_nodes.nodes.florence2 import FlorencePredictor
|
||||
from ComfyUI_VLM_nodes.nodes.runtime import tensor_batch_to_pil
|
||||
|
||||
label = {
|
||||
"florence-base": "Florence-2 base FT (fast)",
|
||||
"florence-large": "Florence-2 large FT (recommended)",
|
||||
}[backend]
|
||||
predictor = FlorencePredictor(label)
|
||||
try:
|
||||
raw, parsed = predictor.run(
|
||||
tensor_batch_to_pil(image)[0],
|
||||
"<MORE_DETAILED_CAPTION>",
|
||||
"",
|
||||
96,
|
||||
3,
|
||||
)
|
||||
return {"response": raw, "parsed": parsed}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "moondream2":
|
||||
from ComfyUI_VLM_nodes.nodes.moondream2 import Moondream2Predictor
|
||||
|
||||
predictor = Moondream2Predictor()
|
||||
try:
|
||||
return {"response": predictor.generate(image, prompt)}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend.startswith("qwen2vl-"):
|
||||
from ComfyUI_VLM_nodes.nodes.qwen2vl import Qwen2VLPredictor
|
||||
|
||||
model_name, memory_mode = {
|
||||
"qwen2vl-2b": ("Qwen2-VL-2B", "ComfyUI managed (BF16)"),
|
||||
"qwen2vl-2b-video": (
|
||||
"Qwen2-VL-2B",
|
||||
"ComfyUI managed (BF16)",
|
||||
),
|
||||
"qwen2vl-7b-4bit": ("Qwen2-VL-7B", "Maximum Savings (4-bit)"),
|
||||
}[backend]
|
||||
predictor = Qwen2VLPredictor(
|
||||
model_name,
|
||||
memory_mode,
|
||||
"Auto (SDPA)",
|
||||
256 * 28 * 28,
|
||||
1280 * 28 * 28,
|
||||
)
|
||||
try:
|
||||
if backend.endswith("-video"):
|
||||
return {
|
||||
"response": predictor.generate_video(
|
||||
None,
|
||||
test_video(),
|
||||
(
|
||||
"What color object moves horizontally? Answer with "
|
||||
"the color and shape."
|
||||
),
|
||||
48,
|
||||
0.0,
|
||||
0.9,
|
||||
2.0,
|
||||
)
|
||||
}
|
||||
return {
|
||||
"response": predictor.generate_images(
|
||||
image, prompt, 48, 0.0, 0.9
|
||||
)
|
||||
}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend.startswith("molmo-"):
|
||||
from ComfyUI_VLM_nodes.nodes.molmo import MolmoPredictor
|
||||
from ComfyUI_VLM_nodes.nodes.runtime import tensor_batch_to_pil
|
||||
|
||||
model_name, memory_mode = {
|
||||
"molmo-1b": (
|
||||
"MolmoE-1B (Efficient)",
|
||||
"Full Precision (45GB+ Required)",
|
||||
),
|
||||
"molmo-7b-d-4bit": (
|
||||
"Molmo-7B-D (Best 7B)",
|
||||
"4-bit Quantized (15GB+ Required)",
|
||||
),
|
||||
"molmo-7b-o-4bit": (
|
||||
"Molmo-7B-O (Alternative 7B)",
|
||||
"4-bit Quantized (15GB+ Required)",
|
||||
),
|
||||
}[backend]
|
||||
predictor = MolmoPredictor(model_name, memory_mode, True)
|
||||
try:
|
||||
response = predictor.generate(
|
||||
tensor_batch_to_pil(image)[0], prompt, 48, 0.0, 0.9, 20
|
||||
)
|
||||
return {"response": response}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "kosmos2":
|
||||
from ComfyUI_VLM_nodes.nodes.kosmos2 import KosmosModelPredictor
|
||||
|
||||
predictor = KosmosModelPredictor()
|
||||
try:
|
||||
return {"response": predictor.generate(image, prompt, 48)}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "uform":
|
||||
from ComfyUI_VLM_nodes.nodes.uform import UformGen2QwenChat
|
||||
|
||||
predictor = UformGen2QwenChat()
|
||||
try:
|
||||
return {"response": predictor.chat(image, prompt, 48)}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "mcllava":
|
||||
from ComfyUI_VLM_nodes.nodes.mcllava import MCLLaVAModelPredictor
|
||||
|
||||
predictor = MCLLaVAModelPredictor()
|
||||
try:
|
||||
return {
|
||||
"response": predictor.generate(
|
||||
image, prompt, 0.0, 0.9, 4, 728, 48
|
||||
)
|
||||
}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "joytag":
|
||||
from ComfyUI_VLM_nodes.nodes.joytag import JoyTagPredictor
|
||||
|
||||
predictor = JoyTagPredictor()
|
||||
try:
|
||||
return {"response": predictor.predict(image, 10, 0.1)}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "paligemma-caption":
|
||||
from ComfyUI_VLM_nodes.nodes.paligemma import (
|
||||
PALIGEMMA_MODELS,
|
||||
PaliPredictor,
|
||||
)
|
||||
from ComfyUI_VLM_nodes.nodes.runtime import tensor_batch_to_pil
|
||||
|
||||
predictor = PaliPredictor(PALIGEMMA_MODELS[0], "bfloat16", "None")
|
||||
try:
|
||||
return {
|
||||
"response": predictor.generate(
|
||||
tensor_batch_to_pil(image)[0],
|
||||
"caption en",
|
||||
max_new_tokens=64,
|
||||
do_sample=False,
|
||||
)
|
||||
}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "minicpm-gguf-q4":
|
||||
from ComfyUI_VLM_nodes.nodes.minicpm import MiniCPMPredictor
|
||||
|
||||
predictor = MiniCPMPredictor("Q4_K_M (4.7GB)", 4096, -1, 8)
|
||||
try:
|
||||
return {
|
||||
"response": predictor.generate(
|
||||
image, prompt, 0.0, 0.9, 40, 1.05, 48
|
||||
)
|
||||
}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
if backend == "audioldm2":
|
||||
from ComfyUI_VLM_nodes.nodes.audioldm2 import AudioLDM2Predictor
|
||||
|
||||
predictor = AudioLDM2Predictor(cpu_offload=True)
|
||||
try:
|
||||
audio, sample_rate = predictor.generate(
|
||||
"a short clean bell chime",
|
||||
"",
|
||||
1.0,
|
||||
2.5,
|
||||
123,
|
||||
1,
|
||||
2,
|
||||
)
|
||||
return {
|
||||
"response": f"audio {audio.shape}",
|
||||
"sample_rate": sample_rate,
|
||||
"finite": bool(torch.isfinite(torch.from_numpy(audio)).all()),
|
||||
}
|
||||
finally:
|
||||
predictor.close()
|
||||
|
||||
raise AssertionError(f"Unhandled backend: {backend}")
|
||||
|
||||
|
||||
def main() -> int:
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--backend", required=True, choices=BACKENDS)
|
||||
args = parser.parse_args()
|
||||
|
||||
started = time.perf_counter()
|
||||
if torch.cuda.is_available():
|
||||
torch.cuda.reset_peak_memory_stats()
|
||||
free_before, total = torch.cuda.mem_get_info()
|
||||
else:
|
||||
free_before = total = 0
|
||||
|
||||
result = _run(args.backend)
|
||||
response = str(result.get("response", ""))
|
||||
if not response.strip():
|
||||
raise RuntimeError("The model returned an empty response.")
|
||||
expected = "green" if args.backend.endswith("-video") else "red"
|
||||
if args.backend != "audioldm2" and expected not in response.lower():
|
||||
raise RuntimeError(
|
||||
f"The model did not identify the {expected} test object: {response}"
|
||||
)
|
||||
if args.backend == "audioldm2" and not result["finite"]:
|
||||
raise RuntimeError("AudioLDM2 returned non-finite samples.")
|
||||
|
||||
if torch.cuda.is_available():
|
||||
peak = torch.cuda.max_memory_allocated()
|
||||
free_after, _ = torch.cuda.mem_get_info()
|
||||
else:
|
||||
peak = free_after = 0
|
||||
result.update(
|
||||
backend=args.backend,
|
||||
seconds=round(time.perf_counter() - started, 2),
|
||||
cuda_total_gib=round(total / 1024**3, 2),
|
||||
cuda_free_before_gib=round(free_before / 1024**3, 2),
|
||||
cuda_free_after_gib=round(free_after / 1024**3, 2),
|
||||
cuda_peak_allocated_gib=round(peak / 1024**3, 2),
|
||||
)
|
||||
print("SPECIALIZED_SMOKE_JSON=" + json.dumps(result, ensure_ascii=False, default=str))
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
@@ -0,0 +1,176 @@
|
||||
"""Run adaptive temporal reasoning on a real local video and real VLM.
|
||||
|
||||
Example:
|
||||
python tests/manual_video_intelligence_smoke.py \
|
||||
/mnt/d/002.mp4 \
|
||||
--model "Qwen 3 VL 2B Instruct" \
|
||||
--output /mnt/d/comfyui-repair/video-intelligence-audit/result.json
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import importlib.util
|
||||
import json
|
||||
import sys
|
||||
import time
|
||||
from pathlib import Path
|
||||
|
||||
import av
|
||||
import torch
|
||||
|
||||
REPOSITORY = Path(__file__).resolve().parents[1]
|
||||
if REPOSITORY.name != "ComfyUI_VLM_nodes":
|
||||
specification = importlib.util.spec_from_file_location(
|
||||
"ComfyUI_VLM_nodes",
|
||||
REPOSITORY / "__init__.py",
|
||||
submodule_search_locations=[str(REPOSITORY)],
|
||||
)
|
||||
if specification is None or specification.loader is None:
|
||||
raise RuntimeError(f"Could not load package from {REPOSITORY}.")
|
||||
package = importlib.util.module_from_spec(specification)
|
||||
sys.modules["ComfyUI_VLM_nodes"] = package
|
||||
specification.loader.exec_module(package)
|
||||
|
||||
from ComfyUI_VLM_nodes.nodes.modern_vlm import ModernVLMPredictor
|
||||
from ComfyUI_VLM_nodes.nodes.video_intelligence import (
|
||||
build_video_reasoning_prompt,
|
||||
parse_video_reasoning_output,
|
||||
resize_video_for_analysis,
|
||||
sample_video_frames,
|
||||
)
|
||||
|
||||
|
||||
def load_video(path: Path) -> tuple[torch.Tensor, float]:
|
||||
container = av.open(str(path))
|
||||
try:
|
||||
stream = container.streams.video[0]
|
||||
rate = stream.average_rate or stream.guessed_rate
|
||||
if rate is None:
|
||||
raise RuntimeError("The video does not report a frame rate.")
|
||||
frames = [
|
||||
torch.from_numpy(frame.to_ndarray(format="rgb24")).to(torch.float32)
|
||||
/ 255.0
|
||||
for frame in container.decode(stream)
|
||||
]
|
||||
finally:
|
||||
container.close()
|
||||
if not frames:
|
||||
raise RuntimeError("The video contains no decodable frames.")
|
||||
return torch.stack(frames), float(rate)
|
||||
|
||||
|
||||
def main() -> int:
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("video", type=Path)
|
||||
parser.add_argument(
|
||||
"--model",
|
||||
default="Qwen 3 VL 2B Instruct",
|
||||
)
|
||||
parser.add_argument("--max-frames", type=int, default=12)
|
||||
parser.add_argument("--analysis-max-side", type=int, default=448)
|
||||
parser.add_argument("--max-new-tokens", type=int, default=512)
|
||||
parser.add_argument("--output", type=Path)
|
||||
args = parser.parse_args()
|
||||
|
||||
frames, fps = load_video(args.video)
|
||||
sampled, selection, diagnostics = sample_video_frames(
|
||||
frames,
|
||||
fps=fps,
|
||||
max_frames=args.max_frames,
|
||||
strategy="Hybrid: scene + motion + tracks",
|
||||
minimum_gap_seconds=0.2,
|
||||
)
|
||||
prompt = build_video_reasoning_prompt(
|
||||
selection,
|
||||
task="Detailed temporal summary",
|
||||
question="What happens, and how do the people behave over time?",
|
||||
max_events=12,
|
||||
)
|
||||
analysis_frames = resize_video_for_analysis(
|
||||
sampled,
|
||||
max_side=args.analysis_max_side,
|
||||
)
|
||||
predictor = ModernVLMPredictor(
|
||||
args.model,
|
||||
"",
|
||||
"ComfyUI managed (BF16)",
|
||||
"Auto (SDPA)",
|
||||
)
|
||||
started = time.perf_counter()
|
||||
try:
|
||||
raw = predictor.generate(
|
||||
images=None,
|
||||
prompt=prompt,
|
||||
system_prompt=(
|
||||
"You are a precise temporal video analyst. Return one JSON "
|
||||
"object that obeys the supplied schema."
|
||||
),
|
||||
max_new_tokens=args.max_new_tokens,
|
||||
temperature=0.0,
|
||||
top_p=1.0,
|
||||
video_frames=analysis_frames,
|
||||
fps=fps,
|
||||
video_selection=selection,
|
||||
)
|
||||
finally:
|
||||
predictor.close()
|
||||
reasoning_seconds = time.perf_counter() - started
|
||||
result = {
|
||||
"video": str(args.video),
|
||||
"model": args.model,
|
||||
"source_shape": list(frames.shape),
|
||||
"fps": fps,
|
||||
"selection": selection.to_dict(),
|
||||
"sampling": diagnostics,
|
||||
"analysis_shape": list(analysis_frames.shape),
|
||||
"reasoning_seconds": reasoning_seconds,
|
||||
"raw_response": raw,
|
||||
"cuda_peak_gib": (
|
||||
torch.cuda.max_memory_allocated() / 2**30
|
||||
if torch.cuda.is_available()
|
||||
else 0.0
|
||||
),
|
||||
}
|
||||
try:
|
||||
summary, events, normalized = parse_video_reasoning_output(raw, selection)
|
||||
except (TypeError, ValueError) as exc:
|
||||
result["structured_output_valid"] = False
|
||||
result["structured_output_error"] = str(exc)
|
||||
if args.output:
|
||||
args.output.parent.mkdir(parents=True, exist_ok=True)
|
||||
args.output.write_text(
|
||||
json.dumps(
|
||||
result,
|
||||
ensure_ascii=False,
|
||||
allow_nan=False,
|
||||
indent=2,
|
||||
sort_keys=True,
|
||||
),
|
||||
encoding="utf-8",
|
||||
)
|
||||
raise
|
||||
result.update(
|
||||
{
|
||||
"structured_output_valid": True,
|
||||
"summary": summary,
|
||||
"events": events.to_dict(),
|
||||
"normalized_response": json.loads(normalized),
|
||||
}
|
||||
)
|
||||
encoded = json.dumps(
|
||||
result,
|
||||
ensure_ascii=False,
|
||||
allow_nan=False,
|
||||
indent=2,
|
||||
sort_keys=True,
|
||||
)
|
||||
if args.output:
|
||||
args.output.parent.mkdir(parents=True, exist_ok=True)
|
||||
args.output.write_text(encoded, encoding="utf-8")
|
||||
print(encoded)
|
||||
return 0
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
raise SystemExit(main())
|
||||
@@ -0,0 +1,111 @@
|
||||
import json
|
||||
import threading
|
||||
import time
|
||||
|
||||
import pytest
|
||||
import torch
|
||||
from ComfyUI_VLM_nodes.nodes.acceleration import (
|
||||
VLMImagePixelBudget,
|
||||
VLMPerformanceProfile,
|
||||
optimize_image_pixels,
|
||||
)
|
||||
from ComfyUI_VLM_nodes.nodes.runtime import (
|
||||
CachedModelNode,
|
||||
tensor_batch_to_pil,
|
||||
tensor_to_pil,
|
||||
)
|
||||
|
||||
|
||||
def test_batch_conversion_matches_single_frame_contract():
|
||||
images = torch.tensor(
|
||||
[
|
||||
[
|
||||
[[float("nan"), 0.5, 2.0], [-1.0, 0.25, 1.0]],
|
||||
[[0.0, 0.0, 0.0], [1.0, 1.0, 1.0]],
|
||||
],
|
||||
[
|
||||
[[255.0, 128.0, 0.0], [0.0, 64.0, 255.0]],
|
||||
[[1.0, 2.0, 3.0], [4.0, 5.0, 6.0]],
|
||||
],
|
||||
]
|
||||
)
|
||||
batch = tensor_batch_to_pil(images)
|
||||
assert len(batch) == 2
|
||||
for index, converted in enumerate(batch):
|
||||
assert converted.mode == "RGB"
|
||||
assert converted.size == (2, 2)
|
||||
assert converted.tobytes() == tensor_to_pil(images, index).tobytes()
|
||||
|
||||
with pytest.raises(IndexError, match="only has batch index 0"):
|
||||
tensor_to_pil(images[0], 1)
|
||||
|
||||
|
||||
def test_pixel_budget_preserves_aspect_and_patch_multiple():
|
||||
images = torch.rand((3, 1080, 1920, 3), dtype=torch.float32)
|
||||
output, report = optimize_image_pixels(
|
||||
images,
|
||||
max_megapixels=0.5,
|
||||
max_edge=1024,
|
||||
multiple=14,
|
||||
resize_quality="Fast (area)",
|
||||
)
|
||||
assert output.ndim == 4
|
||||
assert output.shape[0] == 3
|
||||
assert output.shape[1] % 14 == 0
|
||||
assert output.shape[2] % 14 == 0
|
||||
assert output.shape[1] * output.shape[2] <= 500_000
|
||||
assert output.shape[2] <= 1024
|
||||
assert report["visual_work_reduction"] > 4
|
||||
assert output.shape[2] / output.shape[1] == pytest.approx(16 / 9, rel=0.03)
|
||||
|
||||
|
||||
def test_pixel_budget_never_upscales():
|
||||
image = torch.rand((240, 320, 3), dtype=torch.float32)
|
||||
output, report = optimize_image_pixels(
|
||||
image,
|
||||
max_megapixels=2.0,
|
||||
max_edge=2048,
|
||||
multiple=1,
|
||||
resize_quality="Quality (bicubic)",
|
||||
)
|
||||
assert output is image
|
||||
assert report["resized"] is False
|
||||
|
||||
|
||||
def test_performance_nodes_return_standard_comfy_values():
|
||||
profile = VLMPerformanceProfile().profile("Live / robotics")
|
||||
assert profile[:5] == (24, 0.5, 896, 8, False)
|
||||
assert json.loads(profile[5])["profile"] == "Live / robotics"
|
||||
|
||||
optimized = VLMImagePixelBudget().optimize(
|
||||
torch.rand((1, 1000, 1600, 3)),
|
||||
0.5,
|
||||
1024,
|
||||
"14",
|
||||
"Fast (area)",
|
||||
)
|
||||
assert optimized[1] % 14 == 0
|
||||
assert optimized[2] % 14 == 0
|
||||
|
||||
|
||||
def test_cached_model_node_prevents_duplicate_concurrent_loads():
|
||||
node = CachedModelNode()
|
||||
factory_calls = []
|
||||
handles = []
|
||||
|
||||
def factory():
|
||||
factory_calls.append(1)
|
||||
time.sleep(0.02)
|
||||
return object()
|
||||
|
||||
def load():
|
||||
handles.append(node.get_or_create_model("same-model", factory))
|
||||
|
||||
threads = [threading.Thread(target=load) for _ in range(8)]
|
||||
for thread in threads:
|
||||
thread.start()
|
||||
for thread in threads:
|
||||
thread.join()
|
||||
|
||||
assert len(factory_calls) == 1
|
||||
assert len({id(handle) for handle in handles}) == 1
|
||||
@@ -0,0 +1,250 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
import torch
|
||||
from ComfyUI_VLM_nodes.nodes import florence2
|
||||
from PIL import Image
|
||||
|
||||
EXPECTED_TASKS = {
|
||||
"Caption": ("<CAPTION>", "none"),
|
||||
"Detailed caption": ("<DETAILED_CAPTION>", "none"),
|
||||
"More detailed caption": ("<MORE_DETAILED_CAPTION>", "none"),
|
||||
"OCR": ("<OCR>", "none"),
|
||||
"OCR with regions": ("<OCR_WITH_REGION>", "none"),
|
||||
"Object detection": ("<OD>", "none"),
|
||||
"Dense region caption": ("<DENSE_REGION_CAPTION>", "none"),
|
||||
"Caption to phrase grounding": ("<CAPTION_TO_PHRASE_GROUNDING>", "text"),
|
||||
"Referring expression segmentation": (
|
||||
"<REFERRING_EXPRESSION_SEGMENTATION>",
|
||||
"text",
|
||||
),
|
||||
"Region to segmentation": ("<REGION_TO_SEGMENTATION>", "region"),
|
||||
"Open vocabulary detection": ("<OPEN_VOCABULARY_DETECTION>", "text"),
|
||||
"Region to category": ("<REGION_TO_CATEGORY>", "region"),
|
||||
"Region to description": ("<REGION_TO_DESCRIPTION>", "region"),
|
||||
"Region to OCR": ("<REGION_TO_OCR>", "region"),
|
||||
"Region proposals": ("<REGION_PROPOSAL>", "none"),
|
||||
}
|
||||
|
||||
|
||||
def test_registry_covers_all_official_transformers_tasks():
|
||||
assert len(florence2.TASKS) == 15
|
||||
assert {
|
||||
name: (spec.token, spec.input_kind) for name, spec in florence2.TASKS.items()
|
||||
} == EXPECTED_TASKS
|
||||
assert {spec.output_kind for spec in florence2.TASKS.values()} == {
|
||||
"text",
|
||||
"boxes",
|
||||
"quad_boxes",
|
||||
"polygons",
|
||||
"mixed",
|
||||
}
|
||||
|
||||
|
||||
def test_node_contract_preserves_outputs_and_adds_core_region_input():
|
||||
schema = florence2.Florence2.INPUT_TYPES()
|
||||
assert florence2.NODE_CLASS_MAPPINGS["Florence2"] is florence2.Florence2
|
||||
assert florence2.Florence2.RETURN_TYPES[:4] == (
|
||||
"STRING",
|
||||
"STRING",
|
||||
"MASK",
|
||||
"IMAGE",
|
||||
)
|
||||
assert florence2.Florence2.RETURN_NAMES[:4] == (
|
||||
"text",
|
||||
"structured_json",
|
||||
"mask",
|
||||
"visualization",
|
||||
)
|
||||
assert schema["optional"]["region"][0] == "BOUNDING_BOX"
|
||||
assert "forceInput" not in repr(schema["optional"]["region"])
|
||||
|
||||
|
||||
def test_region_encoding_uses_core_xywh_and_florence_location_bins():
|
||||
region = {"x": 10, "y": 20, "width": 40, "height": 100}
|
||||
assert florence2._encode_region(region, (100, 200)) == (
|
||||
"<loc_100><loc_100><loc_500><loc_600>"
|
||||
)
|
||||
|
||||
clamped = {"x": -10, "y": -20, "width": 200, "height": 300}
|
||||
assert florence2._encode_region(clamped, (100, 200)) == (
|
||||
"<loc_0><loc_0><loc_999><loc_999>"
|
||||
)
|
||||
|
||||
with pytest.raises(ValueError, match="greater than zero"):
|
||||
florence2._encode_region(
|
||||
{"x": 0, "y": 0, "width": 0, "height": 10},
|
||||
(100, 100),
|
||||
)
|
||||
with pytest.raises(ValueError, match="does not overlap"):
|
||||
florence2._encode_region(
|
||||
{"x": 200, "y": 200, "width": 10, "height": 10},
|
||||
(100, 100),
|
||||
)
|
||||
|
||||
|
||||
def test_task_inputs_are_validated_before_inference():
|
||||
image_size = (100, 100)
|
||||
region = {"x": 10, "y": 10, "width": 20, "height": 20}
|
||||
|
||||
assert florence2._task_extra_input("Caption", "", None, image_size) == ""
|
||||
with pytest.raises(ValueError, match="does not accept text"):
|
||||
florence2._task_extra_input("Caption", "unexpected", None, image_size)
|
||||
with pytest.raises(ValueError, match="requires text"):
|
||||
florence2._task_extra_input("Open vocabulary detection", "", None, image_size)
|
||||
assert (
|
||||
florence2._task_extra_input(
|
||||
"Open vocabulary detection", "red car", None, image_size
|
||||
)
|
||||
== "red car"
|
||||
)
|
||||
with pytest.raises(ValueError, match="requires a connected BOUNDING_BOX"):
|
||||
florence2._task_extra_input("Region to OCR", "", None, image_size)
|
||||
assert (
|
||||
florence2._task_extra_input("Region to OCR", "", region, image_size)
|
||||
== "<loc_100><loc_100><loc_300><loc_300>"
|
||||
)
|
||||
with pytest.raises(ValueError, match="does not accept text"):
|
||||
florence2._task_extra_input("Region to OCR", "also text", region, image_size)
|
||||
|
||||
|
||||
def test_region_selection_accepts_core_and_batched_detector_shapes():
|
||||
first = {"x": 1, "y": 2, "width": 3, "height": 4}
|
||||
second = {"x": 5, "y": 6, "width": 7, "height": 8}
|
||||
assert florence2._select_region(first, 0, 2) is first
|
||||
assert florence2._select_region([first, second], 1, 2) is second
|
||||
assert florence2._select_region([[first], [second]], 0, 2) is first
|
||||
|
||||
with pytest.raises(ValueError, match="exactly one"):
|
||||
florence2._select_region([[first, second]], 0, 1)
|
||||
|
||||
|
||||
def test_visualization_is_deterministic_and_masks_every_spatial_shape():
|
||||
image = Image.new("RGB", (48, 36), "black")
|
||||
parsed = {
|
||||
"<OPEN_VOCABULARY_DETECTION>": {
|
||||
"bboxes": [[1, 1, 10, 10]],
|
||||
"bboxes_labels": ["box"],
|
||||
"quad_boxes": [[14, 1, 22, 1, 22, 10, 14, 10]],
|
||||
"labels": ["ocr"],
|
||||
"polygons": [[[26, 1, 40, 1, 40, 12, 26, 12]]],
|
||||
"polygons_labels": ["polygon"],
|
||||
}
|
||||
}
|
||||
|
||||
mask_a, visual_a = florence2._visualize(image, parsed)
|
||||
mask_b, visual_b = florence2._visualize(image, parsed)
|
||||
mask = np.asarray(mask_a)
|
||||
|
||||
assert mask[5, 5] == 255
|
||||
assert mask[5, 18] == 255
|
||||
assert mask[5, 30] == 255
|
||||
assert mask_a.tobytes() == mask_b.tobytes()
|
||||
assert visual_a.tobytes() == visual_b.tobytes()
|
||||
|
||||
|
||||
def test_predictor_generation_is_deterministic_without_downloads():
|
||||
calls = {}
|
||||
|
||||
class FakeProcessor:
|
||||
def __call__(self, text, images, return_tensors):
|
||||
calls["prompt"] = text
|
||||
assert images.size == (8, 8)
|
||||
assert return_tensors == "pt"
|
||||
return {
|
||||
"input_ids": torch.tensor([[1]], dtype=torch.long),
|
||||
"pixel_values": torch.zeros((1, 3, 8, 8)),
|
||||
}
|
||||
|
||||
def batch_decode(self, generated, skip_special_tokens):
|
||||
assert skip_special_tokens is False
|
||||
return ["<s>answer</s>"]
|
||||
|
||||
def post_process_generation(self, raw, task, image_size):
|
||||
return {task: "answer"}
|
||||
|
||||
class FakeModel(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.anchor = torch.nn.Parameter(torch.zeros(()))
|
||||
|
||||
def generate(self, **kwargs):
|
||||
calls["generation"] = kwargs
|
||||
return torch.tensor([[2]], dtype=torch.long)
|
||||
|
||||
class FakeHandle:
|
||||
def __init__(self):
|
||||
self.model = FakeModel()
|
||||
|
||||
def ensure_loaded(self):
|
||||
return self.model
|
||||
|
||||
predictor = object.__new__(florence2.FlorencePredictor)
|
||||
predictor.dtype = torch.float32
|
||||
predictor.processor = FakeProcessor()
|
||||
predictor.handle = FakeHandle()
|
||||
|
||||
raw, parsed = predictor.run(
|
||||
Image.new("RGB", (8, 8)),
|
||||
"<CAPTION>",
|
||||
"",
|
||||
32,
|
||||
3,
|
||||
)
|
||||
assert raw == "<s>answer</s>"
|
||||
assert parsed == {"<CAPTION>": "answer"}
|
||||
assert calls["prompt"] == "<CAPTION>"
|
||||
assert calls["generation"]["do_sample"] is False
|
||||
assert calls["generation"]["num_beams"] == 3
|
||||
assert calls["generation"]["early_stopping"] is True
|
||||
|
||||
|
||||
def test_node_cleans_text_preserves_structured_data_and_unloads_target():
|
||||
parsed = {
|
||||
"<OD>": {
|
||||
"bboxes": [[2, 2, 12, 12]],
|
||||
"labels": ["person"],
|
||||
"quad_boxes": [[14, 2, 22, 2, 22, 12, 14, 12]],
|
||||
"polygons": [[[24, 2, 30, 2, 30, 12, 24, 12]]],
|
||||
}
|
||||
}
|
||||
calls = []
|
||||
|
||||
class FakePredictor:
|
||||
def run(
|
||||
self,
|
||||
image,
|
||||
task_token,
|
||||
extra_input,
|
||||
max_new_tokens,
|
||||
beams,
|
||||
):
|
||||
calls.append((image.size, task_token, extra_input, max_new_tokens, beams))
|
||||
return "<s>person<loc_1><loc_2></s><pad>", parsed
|
||||
|
||||
node = florence2.Florence2()
|
||||
node.get_or_create_model = lambda key, factory: FakePredictor()
|
||||
unloads = []
|
||||
node.maybe_clear_model = unloads.append
|
||||
|
||||
output = node.run(
|
||||
torch.zeros((1, 32, 32, 3)),
|
||||
"Object detection",
|
||||
"",
|
||||
"Florence-2 base FT (fast)",
|
||||
64,
|
||||
1,
|
||||
unload_after=True,
|
||||
)
|
||||
|
||||
assert len(output) == 4
|
||||
assert output[0] == "person<loc_1><loc_2>"
|
||||
assert json.loads(output[1]) == [parsed]
|
||||
assert output[2].shape == (1, 32, 32)
|
||||
assert output[2].max().item() == 1.0
|
||||
assert output[3].shape == (1, 32, 32, 3)
|
||||
assert calls == [((32, 32), "<OD>", "", 64, 1)]
|
||||
assert unloads == [True]
|
||||
@@ -0,0 +1,166 @@
|
||||
import importlib
|
||||
from pathlib import Path
|
||||
|
||||
import pytest
|
||||
import torch
|
||||
|
||||
PACKAGE = Path(__file__).resolve().parents[1].name
|
||||
geometry = importlib.import_module(f"{PACKAGE}.nodes.geometry")
|
||||
vision_types = importlib.import_module(f"{PACKAGE}.nodes.vision_types")
|
||||
|
||||
associate_detections = geometry.associate_detections
|
||||
bbox_from_mask = geometry.bbox_from_mask
|
||||
bbox_iou = geometry.bbox_iou
|
||||
box_area = geometry.box_area
|
||||
box_center = geometry.box_center
|
||||
box_to_mask = geometry.box_to_mask
|
||||
clip_box = geometry.clip_box
|
||||
clip_polygon = geometry.clip_polygon
|
||||
denormalize_box = geometry.denormalize_box
|
||||
detection_to_mask = geometry.detection_to_mask
|
||||
deterministic_color = geometry.deterministic_color
|
||||
expand_box = geometry.expand_box
|
||||
individual_detection_masks = geometry.individual_detection_masks
|
||||
mask_iou = geometry.mask_iou
|
||||
normalize_box = geometry.normalize_box
|
||||
polygon_area = geometry.polygon_area
|
||||
polygon_to_mask = geometry.polygon_to_mask
|
||||
quad_to_mask = geometry.quad_to_mask
|
||||
translate_box = geometry.translate_box
|
||||
union_detection_mask = geometry.union_detection_mask
|
||||
Detection = vision_types.Detection
|
||||
|
||||
|
||||
def test_box_clipping_normalization_area_and_center():
|
||||
assert clip_box((0, 2, 25, 22), 20, 10) == (0, 2, 20, 10)
|
||||
normalized = normalize_box((5, 2, 15, 8), 20, 10)
|
||||
assert normalized == pytest.approx((0.25, 0.2, 0.75, 0.8))
|
||||
assert denormalize_box(normalized, 20, 10) == pytest.approx((5, 2, 15, 8))
|
||||
assert box_area((5, 2, 15, 8)) == 60
|
||||
assert box_center((5, 2, 15, 8)) == (10, 5)
|
||||
with pytest.raises(ValueError, match="Normalized"):
|
||||
denormalize_box((0, 0, 2, 1), 20, 10)
|
||||
with pytest.raises(ValueError, match="x2"):
|
||||
clip_box((2, 0, 1, 1), 20, 10)
|
||||
|
||||
|
||||
def test_polygon_clipping_and_area():
|
||||
polygon = ((-2, -3), (8, 0), (8, 5), (0, 5))
|
||||
assert clip_polygon(polygon, 6, 4) == (
|
||||
(0, 0),
|
||||
(6, 0),
|
||||
(6, 4),
|
||||
(0, 4),
|
||||
)
|
||||
assert polygon_area(((0, 0), (5, 0), (5, 4), (0, 4))) == 20
|
||||
assert polygon_area(((0, 0), (0, 4), (5, 4), (5, 0))) == 20
|
||||
with pytest.raises(ValueError, match="at least three"):
|
||||
polygon_area(((0, 0), (1, 1)))
|
||||
|
||||
|
||||
def test_bbox_and_mask_iou():
|
||||
assert bbox_iou((0, 0, 10, 10), (5, 0, 15, 10)) == pytest.approx(1 / 3)
|
||||
assert bbox_iou((0, 0, 1, 1), (2, 2, 3, 3)) == 0
|
||||
first = torch.zeros((4, 4))
|
||||
second = torch.zeros((4, 4))
|
||||
first[:2, :2] = 1
|
||||
second[1:3, :2] = 1
|
||||
assert mask_iou(first, second) == pytest.approx(1 / 3)
|
||||
assert mask_iou(torch.zeros((2, 2)), torch.zeros((2, 2))) == 0
|
||||
with pytest.raises(ValueError, match="same shape"):
|
||||
mask_iou(torch.zeros((2, 2)), torch.zeros((3, 2)))
|
||||
|
||||
|
||||
def test_box_polygon_and_quad_rasterization():
|
||||
box = box_to_mask((1.2, 2.1, 4.1, 5.2), 8, 7)
|
||||
assert box.shape == (7, 8)
|
||||
assert box.sum().item() == 16
|
||||
polygon = polygon_to_mask(((1, 1), (5, 1), (5, 5), (1, 5)), 8, 8)
|
||||
quad = quad_to_mask(((1, 1), (5, 1), (5, 5), (1, 5)), 8, 8)
|
||||
assert torch.equal(polygon, quad)
|
||||
assert polygon.sum() > 0
|
||||
with pytest.raises(ValueError, match="exactly four"):
|
||||
quad_to_mask(((0, 0), (1, 0), (1, 1)), 4, 4)
|
||||
|
||||
|
||||
def test_detection_mask_priority_union_individual_and_bbox():
|
||||
explicit = torch.zeros((8, 8))
|
||||
explicit[3:6, 2:5] = 1
|
||||
with_mask = Detection(
|
||||
bbox_xyxy=(0, 0, 8, 8),
|
||||
polygon=((0, 0), (8, 0), (8, 8), (0, 8)),
|
||||
mask=explicit,
|
||||
)
|
||||
polygon_only = Detection(
|
||||
bbox_xyxy=(1, 1, 5, 5),
|
||||
polygon=((1, 1), (5, 1), (5, 5), (1, 5)),
|
||||
)
|
||||
assert torch.equal(detection_to_mask(with_mask, 8, 8), explicit)
|
||||
masks = individual_detection_masks((with_mask, polygon_only), 8, 8)
|
||||
assert masks.shape == (2, 8, 8)
|
||||
union = union_detection_mask((with_mask, polygon_only), 8, 8)
|
||||
assert union.shape == (8, 8)
|
||||
assert torch.all(union >= masks[0])
|
||||
assert individual_detection_masks((), 8, 8).shape == (0, 8, 8)
|
||||
assert union_detection_mask((), 8, 8).sum() == 0
|
||||
assert bbox_from_mask(explicit) == (2, 3, 5, 6)
|
||||
assert bbox_from_mask(torch.zeros((2, 2))) is None
|
||||
|
||||
|
||||
def test_deterministic_color_and_box_expansion():
|
||||
assert deterministic_color("track-1") == deterministic_color("track-1")
|
||||
assert deterministic_color("track-1") != deterministic_color("track-2")
|
||||
assert all(0 <= channel <= 255 for channel in deterministic_color("object"))
|
||||
assert expand_box((4, 4, 8, 6), 12, 12, padding=1) == (3, 3, 9, 7)
|
||||
squared = expand_box((4, 4, 8, 6), 12, 12, square=True)
|
||||
assert squared == (4, 3, 8, 7)
|
||||
assert translate_box((1, 2, 3, 4), 2, 1) == (3, 3, 5, 5)
|
||||
|
||||
|
||||
def test_label_aware_stable_association_with_motion():
|
||||
previous = (
|
||||
Detection(
|
||||
bbox_xyxy=(0, 0, 10, 10),
|
||||
label="cat",
|
||||
track_id=4,
|
||||
),
|
||||
Detection(
|
||||
bbox_xyxy=(20, 0, 30, 10),
|
||||
label="dog",
|
||||
track_id=9,
|
||||
),
|
||||
)
|
||||
current = (
|
||||
Detection(bbox_xyxy=(5, 0, 15, 10), label="cat"),
|
||||
Detection(bbox_xyxy=(20, 0, 30, 10), label="bird"),
|
||||
Detection(bbox_xyxy=(40, 0, 50, 10), label="dog"),
|
||||
)
|
||||
without_motion = associate_detections(
|
||||
previous,
|
||||
current,
|
||||
minimum_iou=0.3,
|
||||
)
|
||||
assert without_motion.matches == ((0, 0, pytest.approx(1 / 3)),)
|
||||
assert without_motion.unmatched_previous == (1,)
|
||||
assert without_motion.unmatched_current == (1, 2)
|
||||
|
||||
with_motion = associate_detections(
|
||||
previous,
|
||||
current,
|
||||
minimum_iou=0.9,
|
||||
motion_by_track={4: (5, 0), 9: (20, 0)},
|
||||
)
|
||||
assert with_motion.matches == (
|
||||
(0, 0, 1.0),
|
||||
(1, 2, 1.0),
|
||||
)
|
||||
assert with_motion.unmatched_previous == ()
|
||||
assert with_motion.unmatched_current == (1,)
|
||||
|
||||
label_agnostic = associate_detections(
|
||||
previous,
|
||||
current,
|
||||
minimum_iou=0.9,
|
||||
label_aware=False,
|
||||
)
|
||||
assert label_agnostic.matches == ((1, 1, 1.0),)
|
||||
@@ -0,0 +1,141 @@
|
||||
from types import SimpleNamespace
|
||||
|
||||
import torch
|
||||
from ComfyUI_VLM_nodes.nodes.grounding import (
|
||||
MODEL_SPECS,
|
||||
VLMOpenVocabularyDetection,
|
||||
core_bounding_box_frames,
|
||||
core_bounding_boxes,
|
||||
detection_box_masks,
|
||||
parse_labels,
|
||||
result_to_detections,
|
||||
)
|
||||
from ComfyUI_VLM_nodes.nodes.vision_types import (
|
||||
DetectionSequence,
|
||||
FrameDetections,
|
||||
)
|
||||
|
||||
|
||||
def test_detector_catalog_is_small_fast_and_portable():
|
||||
assert "Grounding DINO Tiny (fast)" in MODEL_SPECS
|
||||
assert "OmDet Turbo Swin Tiny (fast)" in MODEL_SPECS
|
||||
assert all("/" in spec.model_id for spec in MODEL_SPECS.values())
|
||||
schema = VLMOpenVocabularyDetection.INPUT_TYPES()
|
||||
assert tuple(MODEL_SPECS) == schema["required"]["model"][0]
|
||||
|
||||
|
||||
def test_label_parser_preserves_phrases_and_removes_duplicates():
|
||||
assert parse_labels("red car, person\nsmall dog;person") == [
|
||||
"red car",
|
||||
"person",
|
||||
"small dog",
|
||||
]
|
||||
|
||||
|
||||
def test_transformers_results_are_clipped_sorted_and_normalized():
|
||||
result = {
|
||||
"boxes": torch.tensor([[-5.0, 2.0, 20.0, 12.0], [5.0, 5.0, 9.0, 9.0]]),
|
||||
"scores": torch.tensor([0.25, 0.9]),
|
||||
"text_labels": ["cat", "dog"],
|
||||
}
|
||||
detections = result_to_detections(
|
||||
result,
|
||||
labels=["cat", "dog"],
|
||||
width=16,
|
||||
height=10,
|
||||
frame_index=0,
|
||||
timestamp=0.0,
|
||||
source="test/model",
|
||||
max_detections=20,
|
||||
)
|
||||
assert [item.label for item in detections] == ["dog", "cat"]
|
||||
assert detections[1].bbox_xyxy == (0.0, 2.0, 16.0, 10.0)
|
||||
assert detections[0].metadata["model_id"] == "test/model"
|
||||
|
||||
|
||||
def test_max_detections_is_applied_after_confidence_sorting():
|
||||
detections = result_to_detections(
|
||||
{
|
||||
"boxes": [[0, 0, 1, 1], [1, 1, 2, 2], [2, 2, 3, 3]],
|
||||
"scores": [0.1, 0.9, 0.8],
|
||||
"text_labels": ["low", "best", "second"],
|
||||
},
|
||||
labels=["low", "best", "second"],
|
||||
width=4,
|
||||
height=4,
|
||||
frame_index=0,
|
||||
timestamp=0.0,
|
||||
source="test/model",
|
||||
max_detections=2,
|
||||
)
|
||||
assert [item.label for item in detections] == ["best", "second"]
|
||||
|
||||
|
||||
def test_box_masks_and_core_boxes_keep_geometry_and_metadata():
|
||||
detections = result_to_detections(
|
||||
{
|
||||
"boxes": torch.tensor([[1.0, 2.0, 4.0, 5.0]]),
|
||||
"scores": torch.tensor([0.8]),
|
||||
"labels": torch.tensor([0]),
|
||||
},
|
||||
labels=["cat"],
|
||||
width=8,
|
||||
height=6,
|
||||
frame_index=0,
|
||||
timestamp=0.0,
|
||||
source="test/model",
|
||||
max_detections=5,
|
||||
)
|
||||
sequence = DetectionSequence(
|
||||
width=8,
|
||||
height=6,
|
||||
frames=(
|
||||
FrameDetections(
|
||||
frame_index=0,
|
||||
timestamp=0.0,
|
||||
width=8,
|
||||
height=6,
|
||||
detections=detections,
|
||||
),
|
||||
),
|
||||
frame_count=1,
|
||||
)
|
||||
masks = detection_box_masks(sequence)
|
||||
assert masks.shape == (1, 6, 8)
|
||||
assert masks.sum().item() == 9
|
||||
boxes = core_bounding_boxes(sequence)
|
||||
assert boxes == [
|
||||
{
|
||||
"x": 1,
|
||||
"y": 2,
|
||||
"width": 3,
|
||||
"height": 3,
|
||||
"label": "cat",
|
||||
"score": detections[0].score,
|
||||
"metadata": {
|
||||
"frame_index": 0,
|
||||
"label": "cat",
|
||||
"score": detections[0].score,
|
||||
"source": "test/model",
|
||||
},
|
||||
}
|
||||
]
|
||||
assert core_bounding_box_frames(sequence) == [boxes]
|
||||
|
||||
|
||||
def test_result_label_indices_are_resolved():
|
||||
detections = result_to_detections(
|
||||
{
|
||||
"boxes": [[0, 0, 4, 4]],
|
||||
"scores": [SimpleNamespace(item=lambda: 0.5)],
|
||||
"classes": [SimpleNamespace(item=lambda: 1)],
|
||||
},
|
||||
labels=["cat", "dog"],
|
||||
width=4,
|
||||
height=4,
|
||||
frame_index=0,
|
||||
timestamp=0.0,
|
||||
source="omdet",
|
||||
max_detections=1,
|
||||
)
|
||||
assert detections[0].label == "dog"
|
||||
@@ -0,0 +1,905 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
from pathlib import Path
|
||||
from types import SimpleNamespace
|
||||
|
||||
import pytest
|
||||
import torch
|
||||
|
||||
from ComfyUI_VLM_nodes.nodes import hosted_api
|
||||
|
||||
|
||||
class FakeHttpClient:
|
||||
def __init__(self, **kwargs):
|
||||
self.kwargs = kwargs
|
||||
|
||||
|
||||
class FakeResponses:
|
||||
def __init__(self, calls, failure=None, response_text="secure response"):
|
||||
self.calls = calls
|
||||
self.failure = failure
|
||||
self.response_text = response_text
|
||||
|
||||
def create(self, **kwargs):
|
||||
self.calls.append(("responses", kwargs))
|
||||
if self.failure is not None:
|
||||
raise self.failure
|
||||
return SimpleNamespace(output_text=self.response_text)
|
||||
|
||||
|
||||
class FakeChatCompletions:
|
||||
def __init__(self, calls, failure=None, response_text="secure response"):
|
||||
self.calls = calls
|
||||
self.failure = failure
|
||||
self.response_text = response_text
|
||||
|
||||
def create(self, **kwargs):
|
||||
self.calls.append(("chat", kwargs))
|
||||
if self.failure is not None:
|
||||
raise self.failure
|
||||
message = SimpleNamespace(content=self.response_text)
|
||||
return SimpleNamespace(choices=[SimpleNamespace(message=message)])
|
||||
|
||||
|
||||
def fake_openai_module(calls, failure=None, response_text="secure response"):
|
||||
class FakeOpenAI:
|
||||
def __init__(self, **kwargs):
|
||||
calls.append(("client", kwargs))
|
||||
self.responses = FakeResponses(
|
||||
calls,
|
||||
failure=failure,
|
||||
response_text=response_text,
|
||||
)
|
||||
self.chat = SimpleNamespace(
|
||||
completions=FakeChatCompletions(
|
||||
calls,
|
||||
failure=failure,
|
||||
response_text=response_text,
|
||||
)
|
||||
)
|
||||
|
||||
def close(self):
|
||||
calls.append(("close", {}))
|
||||
|
||||
return SimpleNamespace(
|
||||
OpenAI=FakeOpenAI,
|
||||
DefaultHttpxClient=FakeHttpClient,
|
||||
)
|
||||
|
||||
|
||||
def test_api_schemas_never_accept_plaintext_keys():
|
||||
for node_class in (hosted_api.PromptGenerateAPI, hosted_api.HostedVLMAPI):
|
||||
schema = node_class.INPUT_TYPES()
|
||||
all_inputs = {
|
||||
**schema.get("required", {}),
|
||||
**schema.get("optional", {}),
|
||||
**schema.get("hidden", {}),
|
||||
}
|
||||
assert "api_key" not in all_inputs
|
||||
assert "credential_source" in all_inputs
|
||||
assert "STRING" not in repr(all_inputs["credential_source"][0])
|
||||
assert "web_search" in all_inputs
|
||||
assert "output_format" in all_inputs
|
||||
assert "json_schema" in all_inputs
|
||||
assert "schema_api_style" in all_inputs
|
||||
|
||||
|
||||
def test_json_schema_parser_blocks_remote_refs_and_bounds_input():
|
||||
for keyword in ("$ref", "$dynamicRef", "$recursiveRef"):
|
||||
with pytest.raises(ValueError, match="only local fragment"):
|
||||
hosted_api.parse_json_schema(
|
||||
"JSON Schema",
|
||||
json.dumps(
|
||||
{
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"payload": {
|
||||
keyword: "https://attacker.example/schema.json"
|
||||
}
|
||||
},
|
||||
}
|
||||
),
|
||||
)
|
||||
with pytest.raises(ValueError, match="64,000"):
|
||||
hosted_api.parse_json_schema("JSON Schema", "x" * 64_001)
|
||||
|
||||
|
||||
def test_local_structured_output_validation_is_strict_and_normalized():
|
||||
schema_text = json.dumps(
|
||||
{
|
||||
"type": "object",
|
||||
"properties": {"count": {"type": "integer"}},
|
||||
"required": ["count"],
|
||||
"additionalProperties": False,
|
||||
}
|
||||
)
|
||||
schema = hosted_api.parse_json_schema("JSON Schema", schema_text)
|
||||
assert hosted_api.validate_structured_output(
|
||||
'```json\n{"count": 2}\n```',
|
||||
"JSON Schema",
|
||||
schema,
|
||||
) == '{\n "count": 2\n}'
|
||||
with pytest.raises(RuntimeError, match=r"\$\.count \(type constraint\)"):
|
||||
hosted_api.validate_structured_output(
|
||||
'{"count": "two"}',
|
||||
"JSON Schema",
|
||||
schema,
|
||||
)
|
||||
with pytest.raises(RuntimeError, match="valid JSON"):
|
||||
hosted_api.validate_structured_output(
|
||||
'{"count":',
|
||||
"JSON Schema",
|
||||
schema,
|
||||
)
|
||||
|
||||
|
||||
def test_provider_catalog_uses_current_bound_credentials_and_endpoints():
|
||||
assert len(hosted_api.PROVIDER_PROFILES) >= 18
|
||||
expected = {
|
||||
"OpenAI": "OPENAI_API_KEY",
|
||||
"Google Gemini": "GEMINI_API_KEY",
|
||||
"Anthropic": "ANTHROPIC_API_KEY",
|
||||
"xAI": "XAI_API_KEY",
|
||||
"DeepSeek": "DEEPSEEK_API_KEY",
|
||||
"Groq": "GROQ_API_KEY",
|
||||
"Mistral": "MISTRAL_API_KEY",
|
||||
"Together AI": "TOGETHER_API_KEY",
|
||||
"OpenRouter": "OPENROUTER_API_KEY",
|
||||
"Custom / Local": "CUSTOM_API_KEY",
|
||||
}
|
||||
providers = {
|
||||
profile.provider: profile.api_key_env
|
||||
for profile in hosted_api.PROVIDER_PROFILES.values()
|
||||
}
|
||||
assert expected.items() <= providers.items()
|
||||
for profile in hosted_api.PROVIDER_PROFILES.values():
|
||||
if profile.base_url is not None:
|
||||
assert profile.base_url.startswith("https://")
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"url",
|
||||
[
|
||||
"http://example.com/v1",
|
||||
"ftp://127.0.0.1/v1",
|
||||
"https://user:secret@example.com/v1",
|
||||
"https://example.com/v1?api_key=secret",
|
||||
"not-a-url",
|
||||
],
|
||||
)
|
||||
def test_custom_endpoint_rejects_unsafe_urls(url):
|
||||
with pytest.raises(ValueError):
|
||||
hosted_api.validate_custom_base_url(url)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"url",
|
||||
[
|
||||
"http://127.0.0.1:8000/v1",
|
||||
"http://[::1]:11434/v1",
|
||||
"http://localhost:1234/v1",
|
||||
"https://example.com/v1/",
|
||||
],
|
||||
)
|
||||
def test_custom_endpoint_accepts_https_or_loopback(url):
|
||||
normalized, loopback = hosted_api.validate_custom_base_url(url)
|
||||
assert normalized.startswith(("http://", "https://"))
|
||||
assert loopback is (url.startswith("http://"))
|
||||
|
||||
|
||||
def test_built_in_key_cannot_be_redirected(monkeypatch):
|
||||
profile = hosted_api.provider_profile("OpenAI — GPT-5.6 Terra")
|
||||
monkeypatch.setenv("OPENAI_API_KEY", "sk-real-secret-value")
|
||||
with pytest.raises(ValueError, match="pinned to official hosts"):
|
||||
hosted_api.resolve_endpoint(profile, "https://attacker.example/v1")
|
||||
|
||||
|
||||
def test_legacy_plaintext_value_is_rejected_without_echo(monkeypatch):
|
||||
profile = hosted_api.provider_profile("OpenAI — GPT-5.6 Terra")
|
||||
secret = "sk-legacy-plaintext-that-must-not-appear"
|
||||
with pytest.raises(ValueError) as captured:
|
||||
hosted_api.resolve_api_key(profile, secret, loopback=False)
|
||||
assert secret not in str(captured.value)
|
||||
assert "legacy plaintext API key was removed" in str(captured.value)
|
||||
|
||||
|
||||
def test_redaction_removes_exact_encoded_and_header_credentials():
|
||||
secret = "sk-ant-example-SECRET_123456789"
|
||||
message = (
|
||||
f"Authorization: Bearer {secret}; api_key={secret}; "
|
||||
f"url=https://user:{secret}@example.com; encoded={secret}"
|
||||
)
|
||||
redacted = hosted_api.redact_sensitive(message, (secret,))
|
||||
assert secret not in redacted
|
||||
assert "Bearer" not in redacted
|
||||
assert "[REDACTED]" in redacted
|
||||
|
||||
|
||||
def test_responses_call_is_stateless_private_and_provider_bound(monkeypatch):
|
||||
calls = []
|
||||
secret = "sk-openai-provider-bound-secret"
|
||||
monkeypatch.setenv("OPENAI_API_KEY", secret)
|
||||
monkeypatch.setattr(
|
||||
hosted_api,
|
||||
"require_module",
|
||||
lambda *_args: fake_openai_module(calls),
|
||||
)
|
||||
|
||||
node = hosted_api.PromptGenerateAPI()
|
||||
assert not hasattr(node, "session_history")
|
||||
result = node.generate_prompt(
|
||||
"OpenAI — GPT-5.6 Terra",
|
||||
False,
|
||||
hosted_api.PROVIDER_CREDENTIAL,
|
||||
"A scene",
|
||||
"Improve it",
|
||||
0,
|
||||
0,
|
||||
stream_output=False,
|
||||
)
|
||||
assert result == ("secure response",)
|
||||
|
||||
client_kwargs = next(payload for kind, payload in calls if kind == "client")
|
||||
assert client_kwargs["api_key"] == secret
|
||||
assert "base_url" not in client_kwargs
|
||||
assert client_kwargs["http_client"].kwargs["follow_redirects"] is False
|
||||
assert client_kwargs["http_client"].kwargs["trust_env"] is False
|
||||
|
||||
request = next(payload for kind, payload in calls if kind == "responses")
|
||||
assert request["model"] == "gpt-5.6-terra"
|
||||
assert request["store"] is False
|
||||
assert "previous_response_id" not in request
|
||||
assert "metadata" not in request
|
||||
|
||||
|
||||
def test_openai_combines_web_search_structured_output_and_stream_contract(
|
||||
monkeypatch,
|
||||
):
|
||||
calls = []
|
||||
monkeypatch.setenv("OPENAI_API_KEY", "sk-test-structured-search")
|
||||
monkeypatch.setattr(
|
||||
hosted_api,
|
||||
"require_module",
|
||||
lambda import_name, *_args: (
|
||||
fake_openai_module(calls, response_text='{"answer":"grounded"}')
|
||||
if import_name == "openai"
|
||||
else __import__(import_name)
|
||||
),
|
||||
)
|
||||
schema = json.dumps(
|
||||
{
|
||||
"type": "object",
|
||||
"properties": {"answer": {"type": "string"}},
|
||||
"required": ["answer"],
|
||||
"additionalProperties": False,
|
||||
}
|
||||
)
|
||||
result = hosted_api.PromptGenerateAPI().generate_prompt(
|
||||
"OpenAI — GPT-5.6 Sol",
|
||||
False,
|
||||
hosted_api.PROVIDER_CREDENTIAL,
|
||||
"Find a current fact",
|
||||
"",
|
||||
0,
|
||||
0,
|
||||
web_search=True,
|
||||
output_format="JSON Schema",
|
||||
json_schema=schema,
|
||||
stream_output=False,
|
||||
)
|
||||
assert result == ('{\n "answer": "grounded"\n}',)
|
||||
request = next(payload for kind, payload in calls if kind == "responses")
|
||||
assert request["tools"] == [{"type": "web_search"}]
|
||||
assert request["text"]["format"]["type"] == "json_schema"
|
||||
assert request["text"]["format"]["strict"] is True
|
||||
assert request["text"]["format"]["schema"]["required"] == ["answer"]
|
||||
assert "JSON Schema:" in request["instructions"]
|
||||
|
||||
|
||||
def test_unsupported_web_search_fails_before_network(monkeypatch):
|
||||
monkeypatch.setenv("DEEPSEEK_API_KEY", "deepseek-test-secret")
|
||||
with pytest.raises(ValueError, match="does not expose native web search"):
|
||||
hosted_api.PromptGenerateAPI().generate_prompt(
|
||||
"DeepSeek — V4 Flash",
|
||||
False,
|
||||
hosted_api.PROVIDER_CREDENTIAL,
|
||||
"Search now",
|
||||
"",
|
||||
0,
|
||||
0,
|
||||
web_search=True,
|
||||
stream_output=False,
|
||||
)
|
||||
|
||||
|
||||
def test_responses_stream_collects_deltas_and_closes():
|
||||
class Stream(list):
|
||||
closed = False
|
||||
|
||||
def close(self):
|
||||
self.closed = True
|
||||
|
||||
stream = Stream(
|
||||
[
|
||||
SimpleNamespace(type="response.created"),
|
||||
SimpleNamespace(type="response.output_text.delta", delta="hello "),
|
||||
SimpleNamespace(type="response.output_text.delta", delta="world"),
|
||||
]
|
||||
)
|
||||
client = SimpleNamespace(
|
||||
responses=SimpleNamespace(create=lambda **kwargs: stream)
|
||||
)
|
||||
assert hosted_api._stream_responses(client, {"model": "test"}, None) == (
|
||||
"hello world"
|
||||
)
|
||||
assert stream.closed is True
|
||||
|
||||
|
||||
def test_chat_stream_collects_deltas_and_closes():
|
||||
class Stream(list):
|
||||
closed = False
|
||||
|
||||
def close(self):
|
||||
self.closed = True
|
||||
|
||||
stream = Stream(
|
||||
[
|
||||
SimpleNamespace(
|
||||
choices=[
|
||||
SimpleNamespace(delta=SimpleNamespace(content="frame "))
|
||||
]
|
||||
),
|
||||
SimpleNamespace(
|
||||
choices=[
|
||||
SimpleNamespace(delta=SimpleNamespace(content="ready"))
|
||||
]
|
||||
),
|
||||
]
|
||||
)
|
||||
client = SimpleNamespace(
|
||||
chat=SimpleNamespace(
|
||||
completions=SimpleNamespace(create=lambda **kwargs: stream)
|
||||
)
|
||||
)
|
||||
assert hosted_api._stream_chat(client, {"model": "test"}, None) == (
|
||||
"frame ready"
|
||||
)
|
||||
assert stream.closed is True
|
||||
|
||||
|
||||
def test_provider_failure_never_echoes_api_key(monkeypatch):
|
||||
calls = []
|
||||
secret = "sk-secret-reflected-by-provider-123456"
|
||||
failure = RuntimeError(f"Authorization: Bearer {secret} api_key={secret}")
|
||||
monkeypatch.setenv("OPENAI_API_KEY", secret)
|
||||
monkeypatch.setattr(
|
||||
hosted_api,
|
||||
"require_module",
|
||||
lambda *_args: fake_openai_module(calls, failure=failure),
|
||||
)
|
||||
|
||||
with pytest.raises(RuntimeError) as captured:
|
||||
hosted_api.PromptGenerateAPI().generate_prompt(
|
||||
"OpenAI — GPT-5.6 Terra",
|
||||
False,
|
||||
hosted_api.PROVIDER_CREDENTIAL,
|
||||
"hello",
|
||||
"",
|
||||
0,
|
||||
0,
|
||||
stream_output=False,
|
||||
)
|
||||
assert secret not in str(captured.value)
|
||||
assert "[REDACTED]" in str(captured.value)
|
||||
|
||||
|
||||
def test_anthropic_uses_native_messages_and_keeps_key_out_of_body(monkeypatch):
|
||||
calls = []
|
||||
secret = "sk-ant-native-secret"
|
||||
|
||||
class FakeResponse:
|
||||
def raise_for_status(self):
|
||||
return None
|
||||
|
||||
def json(self):
|
||||
return {
|
||||
"content": [
|
||||
{"type": "text", "text": "native Anthropic response"}
|
||||
]
|
||||
}
|
||||
|
||||
class FakeClient:
|
||||
def __init__(self, **kwargs):
|
||||
calls.append(("client", kwargs))
|
||||
|
||||
def post(self, url, **kwargs):
|
||||
calls.append(("post", {"url": url, **kwargs}))
|
||||
return FakeResponse()
|
||||
|
||||
def close(self):
|
||||
calls.append(("close", {}))
|
||||
|
||||
monkeypatch.setenv("ANTHROPIC_API_KEY", secret)
|
||||
monkeypatch.setattr(
|
||||
hosted_api,
|
||||
"require_module",
|
||||
lambda import_name, *_args: (
|
||||
SimpleNamespace(Client=FakeClient)
|
||||
if import_name == "httpx"
|
||||
else pytest.fail(f"Unexpected module request: {import_name}")
|
||||
),
|
||||
)
|
||||
result = hosted_api.HostedVLMAPI().analyze(
|
||||
"Anthropic — Claude Sonnet 5",
|
||||
hosted_api.PROVIDER_CREDENTIAL,
|
||||
"Read this image.",
|
||||
"Be concise.",
|
||||
1,
|
||||
512,
|
||||
80,
|
||||
"auto",
|
||||
images=torch.rand((1, 48, 64, 3)),
|
||||
stream_output=False,
|
||||
)
|
||||
assert result == (
|
||||
"native Anthropic response",
|
||||
"claude-sonnet-5",
|
||||
1,
|
||||
)
|
||||
request = next(payload for kind, payload in calls if kind == "post")
|
||||
assert request["url"] == "https://api.anthropic.com/v1/messages"
|
||||
assert request["headers"]["x-api-key"] == secret
|
||||
assert secret not in repr(request["json"])
|
||||
content = request["json"]["messages"][0]["content"]
|
||||
assert content[1]["type"] == "image"
|
||||
assert content[1]["source"]["type"] == "base64"
|
||||
assert request["json"]["stream"] is False
|
||||
|
||||
|
||||
def test_anthropic_native_stream_collects_text_deltas(monkeypatch):
|
||||
class FakeStreamResponse:
|
||||
def __enter__(self):
|
||||
return self
|
||||
|
||||
def __exit__(self, *_args):
|
||||
return False
|
||||
|
||||
def raise_for_status(self):
|
||||
return None
|
||||
|
||||
def iter_lines(self):
|
||||
yield 'event: content_block_delta'
|
||||
yield (
|
||||
'data: {"type":"content_block_delta","delta":'
|
||||
'{"type":"text_delta","text":"hello "}}'
|
||||
)
|
||||
yield (
|
||||
'data: {"type":"content_block_delta","delta":'
|
||||
'{"type":"text_delta","text":"world"}}'
|
||||
)
|
||||
|
||||
class FakeClient:
|
||||
def __init__(self, **_kwargs):
|
||||
pass
|
||||
|
||||
def stream(self, *_args, **_kwargs):
|
||||
return FakeStreamResponse()
|
||||
|
||||
def close(self):
|
||||
return None
|
||||
|
||||
monkeypatch.setattr(
|
||||
hosted_api,
|
||||
"require_module",
|
||||
lambda import_name, *_args: (
|
||||
SimpleNamespace(Client=FakeClient)
|
||||
if import_name == "httpx"
|
||||
else __import__(import_name)
|
||||
),
|
||||
)
|
||||
profile = hosted_api.provider_profile("Anthropic — Claude Sonnet 5")
|
||||
result = hosted_api._call_anthropic_api(
|
||||
profile=profile,
|
||||
model=profile.model,
|
||||
endpoint=profile.base_url,
|
||||
api_key="sk-ant-stream",
|
||||
system_prompt="Be concise.",
|
||||
prompt="Hello",
|
||||
image_data=[],
|
||||
timeout_seconds=30,
|
||||
max_output_tokens=100,
|
||||
stream_output=True,
|
||||
use_system_proxy=False,
|
||||
unique_id=None,
|
||||
web_search=False,
|
||||
output_format="Text",
|
||||
output_schema=None,
|
||||
)
|
||||
assert result == "hello world"
|
||||
|
||||
|
||||
def test_anthropic_native_search_and_structured_contracts(monkeypatch):
|
||||
calls = []
|
||||
|
||||
class FakeResponse:
|
||||
def raise_for_status(self):
|
||||
return None
|
||||
|
||||
def json(self):
|
||||
return {"content": [{"type": "text", "text": '{"answer":"yes"}'}]}
|
||||
|
||||
class FakeClient:
|
||||
def __init__(self, **kwargs):
|
||||
calls.append(("client", kwargs))
|
||||
|
||||
def post(self, url, **kwargs):
|
||||
calls.append(("post", {"url": url, **kwargs}))
|
||||
return FakeResponse()
|
||||
|
||||
def close(self):
|
||||
return None
|
||||
|
||||
monkeypatch.setenv("ANTHROPIC_API_KEY", "sk-ant-contract")
|
||||
monkeypatch.setattr(
|
||||
hosted_api,
|
||||
"require_module",
|
||||
lambda import_name, *_args: (
|
||||
SimpleNamespace(Client=FakeClient)
|
||||
if import_name == "httpx"
|
||||
else __import__(import_name)
|
||||
),
|
||||
)
|
||||
schema = (
|
||||
'{"type":"object","properties":{"answer":{"type":"string"}},'
|
||||
'"required":["answer"],"additionalProperties":false}'
|
||||
)
|
||||
|
||||
result = hosted_api.PromptGenerateAPI().generate_prompt(
|
||||
"Anthropic — Claude Sonnet 5",
|
||||
False,
|
||||
hosted_api.PROVIDER_CREDENTIAL,
|
||||
"Return a value",
|
||||
"",
|
||||
0,
|
||||
0,
|
||||
output_format="JSON Schema",
|
||||
json_schema=schema,
|
||||
stream_output=False,
|
||||
)
|
||||
assert json.loads(result[0]) == {"answer": "yes"}
|
||||
structured = next(payload for kind, payload in calls if kind == "post")
|
||||
assert structured["json"]["output_config"]["format"]["type"] == "json_schema"
|
||||
|
||||
calls.clear()
|
||||
hosted_api.PromptGenerateAPI().generate_prompt(
|
||||
"Anthropic — Claude Sonnet 5",
|
||||
False,
|
||||
hosted_api.PROVIDER_CREDENTIAL,
|
||||
"Search the web",
|
||||
"",
|
||||
0,
|
||||
0,
|
||||
web_search=True,
|
||||
output_format="JSON Schema",
|
||||
json_schema=schema,
|
||||
stream_output=False,
|
||||
)
|
||||
searched = next(payload for kind, payload in calls if kind == "post")
|
||||
assert searched["json"]["tools"][0]["type"] == "web_search_20260318"
|
||||
assert searched["json"]["tools"][0]["allowed_callers"] == ["direct"]
|
||||
assert "output_config" not in searched["json"]
|
||||
|
||||
|
||||
def test_gemini_native_search_vision_and_schema_contract(monkeypatch):
|
||||
calls = []
|
||||
secret = "gemini-provider-secret"
|
||||
|
||||
class FakeResponse:
|
||||
def raise_for_status(self):
|
||||
return None
|
||||
|
||||
def json(self):
|
||||
return {
|
||||
"candidates": [
|
||||
{
|
||||
"content": {
|
||||
"parts": [{"text": '{"objects":["tree"]}'}]
|
||||
}
|
||||
}
|
||||
]
|
||||
}
|
||||
|
||||
class FakeClient:
|
||||
def __init__(self, **kwargs):
|
||||
calls.append(("client", kwargs))
|
||||
|
||||
def post(self, url, **kwargs):
|
||||
calls.append(("post", {"url": url, **kwargs}))
|
||||
return FakeResponse()
|
||||
|
||||
def close(self):
|
||||
return None
|
||||
|
||||
monkeypatch.setenv("GEMINI_API_KEY", secret)
|
||||
monkeypatch.setattr(
|
||||
hosted_api,
|
||||
"require_module",
|
||||
lambda import_name, *_args: (
|
||||
SimpleNamespace(Client=FakeClient)
|
||||
if import_name == "httpx"
|
||||
else __import__(import_name)
|
||||
),
|
||||
)
|
||||
schema = (
|
||||
'{"type":"object","properties":{"objects":{"type":"array",'
|
||||
'"items":{"type":"string"}}},"required":["objects"]}'
|
||||
)
|
||||
result = hosted_api.HostedVLMAPI().analyze(
|
||||
"Google — Gemini 3.6 Flash",
|
||||
hosted_api.PROVIDER_CREDENTIAL,
|
||||
"Identify objects using current context.",
|
||||
"Be precise.",
|
||||
1,
|
||||
512,
|
||||
80,
|
||||
"auto",
|
||||
images=torch.rand((1, 32, 48, 3)),
|
||||
web_search=True,
|
||||
output_format="JSON Schema",
|
||||
json_schema=schema,
|
||||
stream_output=False,
|
||||
)
|
||||
assert json.loads(result[0]) == {"objects": ["tree"]}
|
||||
request = next(payload for kind, payload in calls if kind == "post")
|
||||
assert request["url"].endswith(
|
||||
"/models/gemini-3.6-flash:generateContent"
|
||||
)
|
||||
assert request["headers"]["x-goog-api-key"] == secret
|
||||
assert secret not in repr(request["json"])
|
||||
assert request["json"]["tools"] == [{"google_search": {}}]
|
||||
assert (
|
||||
request["json"]["generationConfig"]["responseFormat"]["text"]["schema"][
|
||||
"required"
|
||||
]
|
||||
== ["objects"]
|
||||
)
|
||||
inline = request["json"]["contents"][0]["parts"][1]["inlineData"]
|
||||
assert inline["mimeType"] == "image/jpeg"
|
||||
assert inline["data"]
|
||||
|
||||
|
||||
def test_gemini_native_stream_collects_sse_deltas(monkeypatch):
|
||||
class FakeStreamResponse:
|
||||
def __enter__(self):
|
||||
return self
|
||||
|
||||
def __exit__(self, *_args):
|
||||
return False
|
||||
|
||||
def raise_for_status(self):
|
||||
return None
|
||||
|
||||
def iter_lines(self):
|
||||
yield (
|
||||
'data: {"candidates":[{"content":{"parts":'
|
||||
'[{"text":"frame "}]}}]}'
|
||||
)
|
||||
yield (
|
||||
'data: {"candidates":[{"content":{"parts":'
|
||||
'[{"text":"ready"}]}}]}'
|
||||
)
|
||||
|
||||
class FakeClient:
|
||||
def __init__(self, **_kwargs):
|
||||
pass
|
||||
|
||||
def stream(self, *_args, **_kwargs):
|
||||
return FakeStreamResponse()
|
||||
|
||||
def close(self):
|
||||
return None
|
||||
|
||||
monkeypatch.setattr(
|
||||
hosted_api,
|
||||
"require_module",
|
||||
lambda import_name, *_args: (
|
||||
SimpleNamespace(Client=FakeClient)
|
||||
if import_name == "httpx"
|
||||
else __import__(import_name)
|
||||
),
|
||||
)
|
||||
profile = hosted_api.provider_profile("Google — Gemini 3.6 Flash")
|
||||
result = hosted_api._call_gemini_api(
|
||||
profile=profile,
|
||||
model=profile.model,
|
||||
api_key="gemini-stream",
|
||||
system_prompt="Be concise.",
|
||||
prompt="Describe.",
|
||||
image_data=[],
|
||||
timeout_seconds=30,
|
||||
max_output_tokens=100,
|
||||
stream_output=True,
|
||||
use_system_proxy=False,
|
||||
unique_id=None,
|
||||
web_search=True,
|
||||
output_format="Text",
|
||||
output_schema=None,
|
||||
)
|
||||
assert result == "frame ready"
|
||||
|
||||
|
||||
def test_vlm_uniformly_samples_and_bounds_image_batch(monkeypatch):
|
||||
calls = []
|
||||
monkeypatch.setenv("OPENAI_API_KEY", "sk-test-only")
|
||||
monkeypatch.setattr(
|
||||
hosted_api,
|
||||
"require_module",
|
||||
lambda *_args: fake_openai_module(calls),
|
||||
)
|
||||
images = torch.rand((10, 96, 128, 3), dtype=torch.float32)
|
||||
result = hosted_api.HostedVLMAPI().analyze(
|
||||
"OpenAI — GPT-5.6 Terra",
|
||||
hosted_api.PROVIDER_CREDENTIAL,
|
||||
"Compare the sampled frames.",
|
||||
"Be precise.",
|
||||
4,
|
||||
768,
|
||||
82,
|
||||
"low",
|
||||
images=images,
|
||||
stream_output=False,
|
||||
)
|
||||
assert result == ("secure response", "gpt-5.6-terra", 4)
|
||||
request = next(payload for kind, payload in calls if kind == "responses")
|
||||
content = request["input"][0]["content"]
|
||||
image_parts = [part for part in content if part["type"] == "input_image"]
|
||||
assert len(image_parts) == 4
|
||||
assert all(part["image_url"].startswith("data:image/jpeg;base64,") for part in image_parts)
|
||||
assert all(part["detail"] == "low" for part in image_parts)
|
||||
|
||||
|
||||
def test_open_source_vlm_llama_cpp_schema_dialect_and_local_validation(
|
||||
monkeypatch,
|
||||
):
|
||||
calls = []
|
||||
monkeypatch.setattr(
|
||||
hosted_api,
|
||||
"require_module",
|
||||
lambda import_name, *_args: (
|
||||
fake_openai_module(calls, response_text='{"objects":["cat"]}')
|
||||
if import_name == "openai"
|
||||
else __import__(import_name)
|
||||
),
|
||||
)
|
||||
schema = json.dumps(
|
||||
{
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"objects": {
|
||||
"type": "array",
|
||||
"items": {"type": "string"},
|
||||
}
|
||||
},
|
||||
"required": ["objects"],
|
||||
"additionalProperties": False,
|
||||
}
|
||||
)
|
||||
result = hosted_api.HostedVLMAPI().analyze(
|
||||
"Custom / Local — OpenAI compatible",
|
||||
hosted_api.LOCAL_NO_KEY,
|
||||
"List visible objects.",
|
||||
"Be precise.",
|
||||
1,
|
||||
512,
|
||||
80,
|
||||
"auto",
|
||||
images=torch.rand((1, 32, 48, 3)),
|
||||
base_url="http://127.0.0.1:8080/v1",
|
||||
model_override="local-vlm",
|
||||
output_format="JSON Schema",
|
||||
json_schema=schema,
|
||||
schema_api_style="llama.cpp JSON Schema",
|
||||
stream_output=False,
|
||||
)
|
||||
assert result == (
|
||||
'{\n "objects": [\n "cat"\n ]\n}',
|
||||
"local-vlm",
|
||||
1,
|
||||
)
|
||||
request = next(payload for kind, payload in calls if kind == "chat")
|
||||
assert request["response_format"] == {
|
||||
"type": "json_schema",
|
||||
"schema": json.loads(schema),
|
||||
}
|
||||
image = request["messages"][1]["content"][1]
|
||||
assert image["type"] == "image_url"
|
||||
assert image["image_url"]["url"].startswith("data:image/jpeg;base64,")
|
||||
|
||||
|
||||
def test_custom_openai_schema_style_uses_standard_wrapper(monkeypatch):
|
||||
calls = []
|
||||
monkeypatch.setattr(
|
||||
hosted_api,
|
||||
"require_module",
|
||||
lambda import_name, *_args: (
|
||||
fake_openai_module(calls, response_text='{"ok":true}')
|
||||
if import_name == "openai"
|
||||
else __import__(import_name)
|
||||
),
|
||||
)
|
||||
schema = '{"type":"object","properties":{"ok":{"type":"boolean"}},"required":["ok"]}'
|
||||
result, _, _ = hosted_api.execute_hosted(
|
||||
model_name="Custom / Local — OpenAI compatible",
|
||||
credential_source=hosted_api.LOCAL_NO_KEY,
|
||||
prompt="Return status.",
|
||||
system_prompt="Be exact.",
|
||||
base_url="http://localhost:8000/v1",
|
||||
model_override="local",
|
||||
api_mode="Chat Completions",
|
||||
timeout_seconds=30,
|
||||
max_output_tokens=100,
|
||||
reasoning_effort="none",
|
||||
seed=0,
|
||||
stream_output=False,
|
||||
use_system_proxy=False,
|
||||
unique_id=None,
|
||||
output_format="JSON Schema",
|
||||
json_schema=schema,
|
||||
)
|
||||
assert json.loads(result) == {"ok": True}
|
||||
request = next(payload for kind, payload in calls if kind == "chat")
|
||||
assert request["response_format"]["json_schema"]["strict"] is True
|
||||
assert request["response_format"]["json_schema"]["schema"]["required"] == [
|
||||
"ok"
|
||||
]
|
||||
|
||||
|
||||
def test_groq_auto_uses_documented_chat_route_for_structured_output(monkeypatch):
|
||||
calls = []
|
||||
monkeypatch.setenv("GROQ_API_KEY", "gsk-test-structured")
|
||||
monkeypatch.setattr(
|
||||
hosted_api,
|
||||
"require_module",
|
||||
lambda import_name, *_args: (
|
||||
fake_openai_module(calls, response_text='{"ok":true}')
|
||||
if import_name == "openai"
|
||||
else __import__(import_name)
|
||||
),
|
||||
)
|
||||
hosted_api.execute_hosted(
|
||||
model_name="Groq — GPT-OSS 20B",
|
||||
credential_source=hosted_api.PROVIDER_CREDENTIAL,
|
||||
prompt="Return status.",
|
||||
system_prompt="Be exact.",
|
||||
base_url="",
|
||||
model_override="",
|
||||
api_mode="Auto",
|
||||
timeout_seconds=30,
|
||||
max_output_tokens=100,
|
||||
reasoning_effort="none",
|
||||
seed=0,
|
||||
stream_output=False,
|
||||
use_system_proxy=False,
|
||||
unique_id=None,
|
||||
output_format="JSON Schema",
|
||||
json_schema=(
|
||||
'{"type":"object","properties":{"ok":{"type":"boolean"}},'
|
||||
'"required":["ok"],"additionalProperties":false}'
|
||||
),
|
||||
)
|
||||
assert any(kind == "chat" for kind, _payload in calls)
|
||||
assert not any(kind == "responses" for kind, _payload in calls)
|
||||
|
||||
|
||||
def test_frontend_scrubs_legacy_key_before_graph_configuration():
|
||||
web_root = Path(__file__).resolve().parents[1] / "web" / "js"
|
||||
source = (
|
||||
web_root / "apiSecurity.js"
|
||||
).read_text("utf-8")
|
||||
assert "beforeConfigureGraph" in source
|
||||
assert "delete values.api_key" in source
|
||||
assert "CREDENTIAL_WIDGET_INDEX = 2" in source
|
||||
view_text = (web_root / "viewText.js").read_text("utf-8")
|
||||
assert '"PromptGenerateAPI"' in view_text
|
||||
assert '"HostedVLMAPI"' in view_text
|
||||
@@ -0,0 +1,77 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import importlib
|
||||
import sys
|
||||
from pathlib import Path
|
||||
from types import ModuleType, SimpleNamespace
|
||||
|
||||
import torch
|
||||
|
||||
PACKAGE = __package__.split(".")[0] if __package__ else "ComfyUI_VLM_nodes"
|
||||
module = importlib.import_module(f"{PACKAGE}.nodes.moondream2")
|
||||
|
||||
|
||||
def test_native_checkpoint_loader_bypasses_transformers_from_pretrained(
|
||||
tmp_path: Path,
|
||||
monkeypatch,
|
||||
):
|
||||
package = ModuleType(module._CHECKPOINT_PACKAGE)
|
||||
package.__path__ = [str(tmp_path.resolve())]
|
||||
package.__package__ = module._CHECKPOINT_PACKAGE
|
||||
checkpoint = ModuleType(f"{module._CHECKPOINT_PACKAGE}.hf_moondream")
|
||||
calls = {}
|
||||
|
||||
class FakeConfig:
|
||||
@classmethod
|
||||
def from_pretrained(cls, model_path, **kwargs):
|
||||
calls["config"] = (Path(model_path), kwargs)
|
||||
return cls()
|
||||
|
||||
class FakeModel(torch.nn.Module):
|
||||
def __init__(self, config):
|
||||
super().__init__()
|
||||
self.weight = torch.nn.Parameter(torch.zeros(1))
|
||||
calls["model_config"] = config
|
||||
|
||||
checkpoint.HfConfig = FakeConfig
|
||||
checkpoint.HfMoondream = FakeModel
|
||||
monkeypatch.setitem(sys.modules, module._CHECKPOINT_PACKAGE, package)
|
||||
monkeypatch.setitem(
|
||||
sys.modules,
|
||||
f"{module._CHECKPOINT_PACKAGE}.hf_moondream",
|
||||
checkpoint,
|
||||
)
|
||||
|
||||
weights = tmp_path / "model.safetensors"
|
||||
weights.write_bytes(b"test")
|
||||
|
||||
def load_model(model, filename, *, strict):
|
||||
calls["weights"] = (model, Path(filename), strict)
|
||||
model.weight.data.fill_(1)
|
||||
return set(), []
|
||||
|
||||
monkeypatch.setattr(
|
||||
module,
|
||||
"require_module",
|
||||
lambda name: (
|
||||
SimpleNamespace(load_model=load_model)
|
||||
if name == "safetensors.torch"
|
||||
else None
|
||||
),
|
||||
)
|
||||
|
||||
model = module._load_native_checkpoint(tmp_path)
|
||||
|
||||
assert isinstance(model, FakeModel)
|
||||
assert not model.training
|
||||
assert model.weight.item() == 1
|
||||
assert calls["config"] == (tmp_path, {"local_files_only": True})
|
||||
assert calls["weights"] == (model, weights, True)
|
||||
|
||||
|
||||
def test_photon_requirements_pin_cuda_runtime_with_required_symbol():
|
||||
requirements = (
|
||||
Path(module.__file__).resolve().parents[1] / "requirements-moondream31.txt"
|
||||
).read_text(encoding="utf-8")
|
||||
assert "kestrel-kernels==0.4.6" in requirements
|
||||
assert "nvidia-cuda-runtime-cu12==12.9.79" in requirements
|
||||
@@ -0,0 +1,361 @@
|
||||
import asyncio
|
||||
import importlib
|
||||
import inspect
|
||||
import json
|
||||
import sys
|
||||
import types
|
||||
from dataclasses import dataclass
|
||||
|
||||
import pytest
|
||||
import torch
|
||||
|
||||
PACKAGE = __package__.split(".")[0] if __package__ else "ComfyUI_VLM_nodes"
|
||||
module = importlib.import_module(f"{PACKAGE}.nodes.moondream31")
|
||||
worker = importlib.import_module(f"{PACKAGE}.nodes.moondream31_worker")
|
||||
|
||||
Moondream31Detect = module.Moondream31Detect
|
||||
Moondream31Loader = module.Moondream31Loader
|
||||
Moondream31Model = module.Moondream31Model
|
||||
Moondream31Segment = module.Moondream31Segment
|
||||
svg_path_to_mask = module.svg_path_to_mask
|
||||
|
||||
|
||||
def _fake_model(handler, model_name=module.MODEL_ID):
|
||||
model = object.__new__(Moondream31Model)
|
||||
model.config = module.Moondream31Config(
|
||||
model=model_name,
|
||||
device="cuda",
|
||||
max_batch_size=4,
|
||||
kv_cache_pages=8192,
|
||||
)
|
||||
model.request = handler
|
||||
model.close = lambda: None
|
||||
return model
|
||||
|
||||
|
||||
def test_svg_path_is_transformed_from_bbox_space_to_image_pixels():
|
||||
mask, polygon, contours = svg_path_to_mask(
|
||||
"M 0 0 H 1 V 1 H 0 Z",
|
||||
{"x_min": 0.25, "y_min": 0.25, "x_max": 0.75, "y_max": 0.75},
|
||||
100,
|
||||
80,
|
||||
supersample=4,
|
||||
)
|
||||
assert mask.shape == (80, 100)
|
||||
assert mask[40, 50] > 0.99
|
||||
assert mask[5, 5] == 0
|
||||
assert mask.sum().item() == pytest.approx(2000, rel=0.06)
|
||||
assert len(polygon) >= 4
|
||||
assert len(contours) == 1
|
||||
xs = [point[0] for point in polygon]
|
||||
ys = [point[1] for point in polygon]
|
||||
assert min(xs) == pytest.approx(25)
|
||||
assert max(xs) == pytest.approx(75)
|
||||
assert min(ys) == pytest.approx(20)
|
||||
assert max(ys) == pytest.approx(60)
|
||||
|
||||
|
||||
def test_svg_curves_and_evenodd_holes_are_preserved():
|
||||
path = "M 0 0 H 1 V 1 H 0 Z M .25 .25 C .4 .1 .6 .1 .75 .25 V .75 H .25 Z"
|
||||
mask, polygon, contours = svg_path_to_mask(
|
||||
path,
|
||||
{"x_min": 0, "y_min": 0, "x_max": 1, "y_max": 1},
|
||||
128,
|
||||
128,
|
||||
supersample=4,
|
||||
precision_px=0.5,
|
||||
)
|
||||
assert len(contours) == 2
|
||||
assert len(polygon) >= 4
|
||||
assert mask[8, 8] > 0.99
|
||||
assert mask[64, 64] < 0.01
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("path", "bbox", "message"),
|
||||
[
|
||||
("", {"x_min": 0, "y_min": 0, "x_max": 1, "y_max": 1}, "empty"),
|
||||
(
|
||||
"M 0 0 L nan 1 Z",
|
||||
{"x_min": 0, "y_min": 0, "x_max": 1, "y_max": 1},
|
||||
"invalid",
|
||||
),
|
||||
(
|
||||
"M 0 0 H 1 V 1 Z",
|
||||
{"x_min": 0.7, "y_min": 0, "x_max": 0.2, "y_max": 1},
|
||||
"positive",
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_svg_rejects_malformed_or_unsafe_geometry(path, bbox, message):
|
||||
with pytest.raises((TypeError, ValueError), match=message):
|
||||
svg_path_to_mask(path, bbox, 64, 64)
|
||||
|
||||
|
||||
def test_video_detect_uses_stride_parallelism_and_reports_measured_fps():
|
||||
observed = {}
|
||||
|
||||
def request(operation, **payload):
|
||||
observed["operation"] = operation
|
||||
observed.update(payload)
|
||||
return {
|
||||
"items": [
|
||||
{
|
||||
"objects": [
|
||||
{
|
||||
"x_min": 0.1,
|
||||
"y_min": 0.2,
|
||||
"x_max": 0.4,
|
||||
"y_max": 0.6,
|
||||
}
|
||||
]
|
||||
},
|
||||
{"objects": []},
|
||||
],
|
||||
"elapsed_seconds": 0.1,
|
||||
"parallel_requests": 2,
|
||||
}
|
||||
|
||||
images = torch.zeros((4, 48, 64, 3), dtype=torch.float32)
|
||||
outputs = Moondream31Detect().detect(
|
||||
_fake_model(request),
|
||||
images,
|
||||
"person",
|
||||
30.0,
|
||||
2,
|
||||
2,
|
||||
20,
|
||||
False,
|
||||
)
|
||||
sequence = outputs[0]
|
||||
performance = json.loads(outputs[-1])
|
||||
assert observed["operation"] == "detect"
|
||||
assert len(observed["images"]) == 2
|
||||
assert observed["parallel_requests"] == 2
|
||||
assert sequence.frame_count == 4
|
||||
assert [frame.frame_index for frame in sequence.frames] == [0, 2]
|
||||
assert sequence.frames[0].detections[0].bbox_xyxy == pytest.approx(
|
||||
(6.4, 9.6, 25.6, 28.8)
|
||||
)
|
||||
assert outputs[2].shape == images.shape
|
||||
assert outputs[3].shape == (4, 48, 64)
|
||||
assert performance["processed_frames"] == 2
|
||||
assert performance["worker_fps"] == pytest.approx(20)
|
||||
assert performance["target_processed_fps"] == pytest.approx(15)
|
||||
assert performance["parallel_requests"] == 2
|
||||
|
||||
|
||||
def test_segment_exposes_svg_mask_cutout_overlay_and_structured_detection():
|
||||
def request(operation, **payload):
|
||||
assert operation == "segment"
|
||||
assert payload["spatial_refs"] == [[0.5, 0.5]]
|
||||
return {
|
||||
"items": [
|
||||
{
|
||||
"path": "M 0 0 H 1 V 1 H 0 Z",
|
||||
"bbox": {
|
||||
"x_min": 0.25,
|
||||
"y_min": 0.25,
|
||||
"x_max": 0.75,
|
||||
"y_max": 0.75,
|
||||
},
|
||||
}
|
||||
],
|
||||
"elapsed_seconds": 0.2,
|
||||
"parallel_requests": 1,
|
||||
}
|
||||
|
||||
image = torch.ones((1, 32, 40, 3), dtype=torch.float32)
|
||||
outputs = Moondream31Segment().segment(
|
||||
_fake_model(request, module.PREVIEW_MODEL_ID),
|
||||
image,
|
||||
"object",
|
||||
1.0,
|
||||
1,
|
||||
1,
|
||||
4,
|
||||
False,
|
||||
spatial_refs_json="[[0.5, 0.5]]",
|
||||
)
|
||||
sequence = outputs[0]
|
||||
native = json.loads(outputs[2])
|
||||
mask = outputs[3]
|
||||
mask_image = outputs[4]
|
||||
cutout = outputs[5]
|
||||
overlay = outputs[6]
|
||||
detection = sequence.frames[0].detections[0]
|
||||
assert native[0]["path"].startswith("M 0 0")
|
||||
assert mask.shape == (1, 32, 40)
|
||||
assert mask_image.shape == (1, 32, 40, 3)
|
||||
assert cutout.shape == image.shape
|
||||
assert overlay.shape == image.shape
|
||||
assert mask[0, 16, 20] > 0.99
|
||||
assert mask[0, 2, 2] == 0
|
||||
assert cutout[0, 16, 20].min() > 0.99
|
||||
assert cutout[0, 2, 2].max() == 0
|
||||
assert detection.mask is not None
|
||||
assert detection.polygon is not None
|
||||
assert detection.metadata["native_svg_path"].startswith("M 0 0")
|
||||
|
||||
|
||||
def test_license_gate_and_node_registration():
|
||||
with pytest.raises(ValueError, match="License"):
|
||||
Moondream31Loader().load(
|
||||
False,
|
||||
"Auto",
|
||||
4,
|
||||
"Balanced (8K pages)",
|
||||
)
|
||||
assert set(module.NODE_CLASS_MAPPINGS) == {
|
||||
"Moondream31Loader",
|
||||
"Moondream31Query",
|
||||
"Moondream31Caption",
|
||||
"Moondream31Detect",
|
||||
"Moondream31Point",
|
||||
"Moondream31Segment",
|
||||
}
|
||||
assert all(
|
||||
node.CATEGORY == "VLM Nodes/Moondream 3"
|
||||
for node in module.NODE_CLASS_MAPPINGS.values()
|
||||
)
|
||||
|
||||
|
||||
def test_final_31_model_does_not_claim_preview_svg_segment():
|
||||
with pytest.raises(ValueError, match="3 Preview"):
|
||||
Moondream31Segment().segment(
|
||||
_fake_model(lambda *_args, **_kwargs: {}),
|
||||
torch.zeros((1, 16, 16, 3)),
|
||||
"object",
|
||||
1.0,
|
||||
1,
|
||||
1,
|
||||
1,
|
||||
False,
|
||||
)
|
||||
|
||||
|
||||
def test_worker_auth_is_not_exposed_in_process_arguments_and_logs_are_redacted(
|
||||
tmp_path,
|
||||
monkeypatch,
|
||||
):
|
||||
source = inspect.getsource(Moondream31Model.ensure_started)
|
||||
assert '"--auth-key"' not in source
|
||||
assert "MOONDREAM_WORKER_AUTH" in inspect.getsource(
|
||||
module._worker_environment
|
||||
)
|
||||
log = tmp_path / "worker.log"
|
||||
log.write_text(
|
||||
"api_key=secret-value\nAuthorization: bearer-value\nCUDA error",
|
||||
encoding="utf-8",
|
||||
)
|
||||
tail = module._safe_log_tail(log)
|
||||
assert "secret-value" not in tail
|
||||
assert "bearer-value" not in tail
|
||||
assert "CUDA error" in tail
|
||||
|
||||
monkeypatch.setenv("PATH", "/runtime/bin")
|
||||
monkeypatch.setenv("OPENAI_API_KEY", "must-not-cross")
|
||||
monkeypatch.setenv("HF_TOKEN", "hf-server-side")
|
||||
monkeypatch.setenv("MOONDREAM_API_KEY", "adapter-only")
|
||||
monkeypatch.setenv("HTTPS_PROXY", "https://user:password@example.test")
|
||||
monkeypatch.setenv("PYTORCH_ALLOC_CONF", "backend:cudaMallocAsync")
|
||||
monkeypatch.setenv("PYTORCH_CUDA_ALLOC_CONF", "backend:cudaMallocAsync")
|
||||
base_environment = module._worker_environment(
|
||||
tmp_path,
|
||||
b"\x01" * 32,
|
||||
module.MODEL_ID,
|
||||
)
|
||||
assert base_environment["PATH"] == "/runtime/bin"
|
||||
assert base_environment["HF_TOKEN"] == "hf-server-side"
|
||||
assert "OPENAI_API_KEY" not in base_environment
|
||||
assert "MOONDREAM_API_KEY" not in base_environment
|
||||
assert "HTTPS_PROXY" not in base_environment
|
||||
assert "PYTORCH_ALLOC_CONF" not in base_environment
|
||||
assert "PYTORCH_CUDA_ALLOC_CONF" not in base_environment
|
||||
assert base_environment["MOONDREAM_WORKER_AUTH"] == "01" * 32
|
||||
|
||||
adapter_environment = module._worker_environment(
|
||||
tmp_path,
|
||||
b"\x02" * 32,
|
||||
f"{module.MODEL_ID}/adapter@step",
|
||||
)
|
||||
assert adapter_environment["MOONDREAM_API_KEY"] == "adapter-only"
|
||||
|
||||
|
||||
def test_runtime_python_preserves_virtualenv_symlink(tmp_path, monkeypatch):
|
||||
root = tmp_path / "runtime"
|
||||
binary = tmp_path / "base-python"
|
||||
binary.write_text("", encoding="utf-8")
|
||||
venv_python = root / ".venv" / "bin" / "python"
|
||||
venv_python.parent.mkdir(parents=True)
|
||||
try:
|
||||
venv_python.symlink_to(binary)
|
||||
except OSError:
|
||||
pytest.skip("This filesystem cannot create symlinks.")
|
||||
monkeypatch.delenv("MOONDREAM_PYTHON", raising=False)
|
||||
selected = module._runtime_python(root)
|
||||
assert selected == venv_python.absolute()
|
||||
assert selected != binary.resolve()
|
||||
|
||||
|
||||
def test_worker_registers_official_31_id_only_when_upstream_is_missing(
|
||||
monkeypatch,
|
||||
):
|
||||
@dataclass(frozen=True)
|
||||
class Spec:
|
||||
name: str
|
||||
repo_id: str
|
||||
filename: str
|
||||
checkpoint_format: str
|
||||
|
||||
registry = {
|
||||
"moondream3-preview": Spec(
|
||||
"moondream3-preview",
|
||||
"moondream/moondream3-preview",
|
||||
"model_fp8.pt",
|
||||
"md3",
|
||||
)
|
||||
}
|
||||
fake = types.ModuleType("kestrel.models")
|
||||
fake.get_spec = lambda name: (
|
||||
registry[name] if name in registry else (_ for _ in ()).throw(ValueError(name))
|
||||
)
|
||||
fake.register = lambda spec: registry.__setitem__(spec.name, spec)
|
||||
monkeypatch.setitem(sys.modules, "kestrel.models", fake)
|
||||
|
||||
assert worker._register_moondream31_if_needed("moondream3.1-9B-A2B")
|
||||
registered = registry["moondream3.1-9B-A2B"]
|
||||
assert registered.repo_id == "moondream/moondream3.1-9B-A2B"
|
||||
assert registered.filename == "model.safetensors"
|
||||
assert registered.checkpoint_format == "md3"
|
||||
assert not worker._register_moondream31_if_needed("moondream3.1-9B-A2B")
|
||||
assert not worker._register_moondream31_if_needed("custom-model")
|
||||
|
||||
|
||||
def test_worker_honors_do_not_track_for_base_models(monkeypatch):
|
||||
class SimpleClient:
|
||||
def __init__(self):
|
||||
self.closed = False
|
||||
|
||||
async def aclose(self):
|
||||
self.closed = True
|
||||
|
||||
class Reporter:
|
||||
def __init__(self):
|
||||
self._client = SimpleClient()
|
||||
|
||||
fake = types.ModuleType("kestrel.photon")
|
||||
fake.PhotonReporter = Reporter
|
||||
monkeypatch.setitem(sys.modules, "kestrel.photon", fake)
|
||||
monkeypatch.setenv("DO_NOT_TRACK", "1")
|
||||
monkeypatch.delenv("MOONDREAM_API_KEY", raising=False)
|
||||
|
||||
assert worker._honor_do_not_track()
|
||||
reporter = Reporter()
|
||||
assert asyncio.run(reporter.validate_api_key()) is False
|
||||
assert reporter.start() is None
|
||||
asyncio.run(reporter.shutdown())
|
||||
assert reporter._client.closed
|
||||
|
||||
monkeypatch.setenv("MOONDREAM_API_KEY", "finetune-key")
|
||||
assert not worker._honor_do_not_track()
|
||||
@@ -0,0 +1,632 @@
|
||||
import base64
|
||||
import inspect
|
||||
import io
|
||||
from contextlib import nullcontext
|
||||
from pathlib import Path
|
||||
from types import SimpleNamespace
|
||||
|
||||
import ComfyUI_VLM_nodes as package
|
||||
import numpy as np
|
||||
import pytest
|
||||
import torch
|
||||
from ComfyUI_VLM_nodes.nodes import (
|
||||
audioldm2,
|
||||
florence2,
|
||||
modern_vlm,
|
||||
paligemma,
|
||||
qwen2vl,
|
||||
)
|
||||
from ComfyUI_VLM_nodes.nodes import (
|
||||
runtime as vlm_runtime,
|
||||
)
|
||||
from ComfyUI_VLM_nodes.nodes.runtime import (
|
||||
LlamaHandle,
|
||||
LlavaClipConfig,
|
||||
accelerator_backend,
|
||||
external_device_map,
|
||||
image_data_uri,
|
||||
llama_chat_content,
|
||||
llama_cpp_diagnostics,
|
||||
pil_mask_to_tensor,
|
||||
pil_to_tensor,
|
||||
runtime_diagnostics,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
from PIL import Image
|
||||
|
||||
|
||||
def test_every_module_imports_and_expected_nodes_exist():
|
||||
assert package.IMPORT_ERRORS == {}
|
||||
expected = {
|
||||
"ModernVLM",
|
||||
"LegacyModernVLM",
|
||||
"VLMRuntimeDiagnostics",
|
||||
"Florence2",
|
||||
"Paligemma",
|
||||
"MolmoNode",
|
||||
"Qwen2VLNode",
|
||||
"Moondream2model",
|
||||
"MiniCPMNode",
|
||||
}
|
||||
assert expected <= package.NODE_CLASS_MAPPINGS.keys()
|
||||
|
||||
|
||||
def test_node_schemas_do_not_use_force_input():
|
||||
for node_class in package.NODE_CLASS_MAPPINGS.values():
|
||||
schema = node_class.INPUT_TYPES()
|
||||
assert "forceInput" not in repr(schema)
|
||||
|
||||
|
||||
def test_source_has_no_runtime_installer_or_direct_cuda_cache():
|
||||
root = Path(package.__file__).parent
|
||||
source = "\n".join(
|
||||
path.read_text(encoding="utf-8", errors="replace")
|
||||
for path in (root / "nodes").rglob("*.py")
|
||||
)
|
||||
assert "torch.cuda.empty_cache" not in source
|
||||
assert "subprocess.run" not in source
|
||||
assert "pip install" not in source
|
||||
|
||||
|
||||
def test_portable_device_dtype_and_backend_contracts(monkeypatch):
|
||||
assert torch_dtype("float16", torch.device("cpu")) == torch.float32
|
||||
assert torch_dtype("float16", torch.device("mps")) == torch.float16
|
||||
assert torch_dtype("float16", torch.device("xpu")) == torch.float16
|
||||
assert accelerator_backend(torch.device("mps")) == "apple-metal"
|
||||
assert accelerator_backend(torch.device("xpu")) == "intel-xpu"
|
||||
|
||||
monkeypatch.setattr(torch.version, "hip", None, raising=False)
|
||||
assert accelerator_backend(torch.device("cuda")) == "nvidia-cuda"
|
||||
monkeypatch.setattr(torch.version, "hip", "7.2", raising=False)
|
||||
assert accelerator_backend(torch.device("cuda")) == "amd-rocm"
|
||||
|
||||
|
||||
def test_runtime_report_and_device_map_are_supportable():
|
||||
report = runtime_diagnostics()
|
||||
assert {
|
||||
"platform",
|
||||
"machine",
|
||||
"python",
|
||||
"torch",
|
||||
"device",
|
||||
"backend",
|
||||
"bf16",
|
||||
"torch_cuda",
|
||||
"torch_hip",
|
||||
"packages",
|
||||
"llama_cpp",
|
||||
} <= report.keys()
|
||||
device_map = external_device_map()
|
||||
assert set(device_map) == {""}
|
||||
assert device_map[""] == report["device"]
|
||||
|
||||
|
||||
def test_dependency_metadata_matches_installer_requirements():
|
||||
try:
|
||||
import tomllib
|
||||
except ModuleNotFoundError:
|
||||
pytest.skip("tomllib is built into Python 3.11+")
|
||||
from packaging.requirements import Requirement
|
||||
|
||||
root = Path(package.__file__).parent
|
||||
metadata = tomllib.loads((root / "pyproject.toml").read_text("utf-8"))
|
||||
project_requirements = {
|
||||
str(Requirement(value)) for value in metadata["project"]["dependencies"]
|
||||
}
|
||||
installer_requirements = {
|
||||
str(Requirement(line))
|
||||
for line in (root / "requirements.txt").read_text("utf-8").splitlines()
|
||||
if line.strip() and not line.lstrip().startswith("#")
|
||||
}
|
||||
assert project_requirements == installer_requirements
|
||||
assert any(
|
||||
Requirement(value).name == "num2words"
|
||||
for value in metadata["project"]["dependencies"]
|
||||
)
|
||||
|
||||
bitsandbytes = next(
|
||||
Requirement(value)
|
||||
for value in metadata["project"]["dependencies"]
|
||||
if Requirement(value).name == "bitsandbytes"
|
||||
)
|
||||
assert bitsandbytes.marker is not None
|
||||
supported = (
|
||||
("linux", "x86_64"),
|
||||
("linux", "aarch64"),
|
||||
("win32", "AMD64"),
|
||||
("win32", "ARM64"),
|
||||
("darwin", "arm64"),
|
||||
)
|
||||
unsupported = (
|
||||
("darwin", "x86_64"),
|
||||
("linux", "ppc64le"),
|
||||
)
|
||||
for system, machine in supported:
|
||||
assert bitsandbytes.marker.evaluate(
|
||||
{"sys_platform": system, "platform_machine": machine}
|
||||
)
|
||||
for system, machine in unsupported:
|
||||
assert not bitsandbytes.marker.evaluate(
|
||||
{"sys_platform": system, "platform_machine": machine}
|
||||
)
|
||||
|
||||
gguf_extra = {
|
||||
str(Requirement(value))
|
||||
for value in metadata["project"]["optional-dependencies"]["gguf"]
|
||||
}
|
||||
gguf_requirements = {
|
||||
str(Requirement(line))
|
||||
for line in (root / "requirements-llama-cpp.txt")
|
||||
.read_text("utf-8")
|
||||
.splitlines()
|
||||
if line.strip() and not line.lstrip().startswith("#")
|
||||
}
|
||||
assert gguf_extra == gguf_requirements
|
||||
|
||||
|
||||
def _fake_llama_module(llama_class, *, gpu=True, mmap=True):
|
||||
return SimpleNamespace(
|
||||
__version__="0.3.34",
|
||||
Llama=llama_class,
|
||||
LLAMA_SPLIT_MODE_LAYER=1,
|
||||
LLAMA_SPLIT_MODE_ROW=2,
|
||||
LLAMA_SPLIT_MODE_NONE=0,
|
||||
llama_supports_gpu_offload=lambda: gpu,
|
||||
llama_supports_mmap=lambda: mmap,
|
||||
llama_supports_mlock=lambda: False,
|
||||
llama_print_system_info=lambda: (
|
||||
b"GGML_CUDA = 1 | BLAS = 1" if gpu else b"BLAS = 1"
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
def test_llama_cpp_diagnostics_reports_its_own_backend():
|
||||
class FakeLlama:
|
||||
pass
|
||||
|
||||
report = llama_cpp_diagnostics(_fake_llama_module(FakeLlama))
|
||||
assert report["version"] == "0.3.34"
|
||||
assert report["gpu_offload"] is True
|
||||
assert report["mmap"] is True
|
||||
assert report["backends"] == ["cuda", "blas"]
|
||||
|
||||
|
||||
def test_llama_chat_content_rejects_empty_or_malformed_responses():
|
||||
assert (
|
||||
llama_chat_content({"choices": [{"message": {"content": " ready "}}]})
|
||||
== "ready"
|
||||
)
|
||||
with pytest.raises(RuntimeError, match="empty response"):
|
||||
llama_chat_content({"choices": [{"message": {"content": None}}]})
|
||||
with pytest.raises(RuntimeError, match="unexpected response"):
|
||||
llama_chat_content({"choices": []})
|
||||
|
||||
|
||||
def test_llama_handle_falls_back_to_cpu_for_cpu_only_build(monkeypatch, tmp_path):
|
||||
calls = []
|
||||
|
||||
class FakeLlama:
|
||||
def __init__(self, **kwargs):
|
||||
calls.append(kwargs)
|
||||
|
||||
def close(self):
|
||||
calls.append("closed")
|
||||
|
||||
module = _fake_llama_module(FakeLlama, gpu=False, mmap=False)
|
||||
monkeypatch.setattr(vlm_runtime, "require_module", lambda *_args: module)
|
||||
reserved = []
|
||||
monkeypatch.setattr(vlm_runtime, "reserve_external_vram", reserved.append)
|
||||
model_path = tmp_path / "model.gguf"
|
||||
model_path.write_bytes(b"gguf")
|
||||
handler_gpu = []
|
||||
|
||||
class Handler:
|
||||
def close(self):
|
||||
handler_gpu.append("closed")
|
||||
|
||||
def handler_factory(*, use_gpu):
|
||||
handler_gpu.append(use_gpu)
|
||||
return Handler()
|
||||
|
||||
handle = LlamaHandle(
|
||||
model_path,
|
||||
n_ctx=0,
|
||||
n_gpu_layers=-1,
|
||||
n_threads=4,
|
||||
n_batch=1024,
|
||||
n_ubatch=768,
|
||||
flash_attention="Auto",
|
||||
use_mmap=True,
|
||||
chat_handler_factory=handler_factory,
|
||||
)
|
||||
handle.ensure_loaded()
|
||||
assert reserved == []
|
||||
assert handler_gpu == [False]
|
||||
assert calls[0]["n_gpu_layers"] == 0
|
||||
assert calls[0]["n_batch"] == 1024
|
||||
assert calls[0]["n_ubatch"] == 768
|
||||
assert calls[0]["offload_kqv"] is False
|
||||
assert calls[0]["op_offload"] is False
|
||||
assert calls[0]["flash_attn"] is False
|
||||
assert calls[0]["use_mmap"] is False
|
||||
handle.close()
|
||||
assert calls[-1] == "closed"
|
||||
assert handler_gpu[-1] == "closed"
|
||||
|
||||
|
||||
def test_llama_handle_uses_accelerator_batching_and_multi_gpu(monkeypatch, tmp_path):
|
||||
calls = []
|
||||
|
||||
class FakeLlama:
|
||||
def __init__(self, **kwargs):
|
||||
calls.append(kwargs)
|
||||
|
||||
module = _fake_llama_module(FakeLlama)
|
||||
monkeypatch.setattr(vlm_runtime, "require_module", lambda *_args: module)
|
||||
reserved = []
|
||||
monkeypatch.setattr(vlm_runtime, "reserve_external_vram", reserved.append)
|
||||
model_path = tmp_path / "model.gguf"
|
||||
projector_path = tmp_path / "mmproj.gguf"
|
||||
model_path.write_bytes(b"1234")
|
||||
projector_path.write_bytes(b"123")
|
||||
handle = LlamaHandle(
|
||||
model_path,
|
||||
n_ctx=256,
|
||||
n_gpu_layers=-1,
|
||||
n_threads=6,
|
||||
n_batch=512,
|
||||
n_ubatch=1024,
|
||||
split_mode="Row",
|
||||
main_gpu=1,
|
||||
tensor_split="0.25, 0.75",
|
||||
projector_path=projector_path,
|
||||
)
|
||||
handle.ensure_loaded()
|
||||
assert reserved == [7]
|
||||
assert calls[0]["n_batch"] == 256
|
||||
assert calls[0]["n_ubatch"] == 256
|
||||
assert "n_threads_batch" not in calls[0]
|
||||
assert calls[0]["split_mode"] == 2
|
||||
assert calls[0]["main_gpu"] == 1
|
||||
assert calls[0]["tensor_split"] == [0.25, 0.75]
|
||||
assert calls[0]["flash_attn"] is True
|
||||
assert calls[0]["offload_kqv"] is True
|
||||
|
||||
|
||||
def test_llama_handle_auto_flash_attention_retries_portably(monkeypatch, tmp_path):
|
||||
calls = []
|
||||
|
||||
class FakeLlama:
|
||||
def __init__(self, **kwargs):
|
||||
calls.append(kwargs)
|
||||
if kwargs["flash_attn"]:
|
||||
raise RuntimeError("flash attention is not supported")
|
||||
|
||||
monkeypatch.setattr(
|
||||
vlm_runtime,
|
||||
"require_module",
|
||||
lambda *_args: _fake_llama_module(FakeLlama),
|
||||
)
|
||||
monkeypatch.setattr(vlm_runtime, "reserve_external_vram", lambda _size: None)
|
||||
model_path = tmp_path / "model.gguf"
|
||||
model_path.write_bytes(b"gguf")
|
||||
LlamaHandle(
|
||||
model_path,
|
||||
n_ctx=128,
|
||||
n_gpu_layers=-1,
|
||||
n_threads=2,
|
||||
).ensure_loaded()
|
||||
assert [call["flash_attn"] for call in calls] == [True, False]
|
||||
|
||||
|
||||
def test_llava_handler_auto_and_explicit_selection(monkeypatch, tmp_path):
|
||||
calls = []
|
||||
|
||||
class MTMD:
|
||||
def __init__(self, **kwargs):
|
||||
calls.append(("auto", kwargs))
|
||||
|
||||
class MiniCPM:
|
||||
def __init__(self, **kwargs):
|
||||
calls.append(("minicpm", kwargs))
|
||||
|
||||
monkeypatch.setattr(
|
||||
vlm_runtime,
|
||||
"require_module",
|
||||
lambda *_args: SimpleNamespace(
|
||||
MTMDChatHandler=MTMD,
|
||||
MiniCPMv26ChatHandler=MiniCPM,
|
||||
),
|
||||
)
|
||||
projector = tmp_path / "mmproj.gguf"
|
||||
projector.write_bytes(b"gguf")
|
||||
LlavaClipConfig(projector, "Auto (GGUF chat template)").create(use_gpu=False)
|
||||
LlavaClipConfig(projector, "MiniCPM-V 2.6").create(use_gpu=True)
|
||||
assert calls[0][0] == "auto"
|
||||
assert calls[0][1]["use_gpu"] is False
|
||||
assert calls[1][0] == "minicpm"
|
||||
|
||||
|
||||
def test_image_roundtrip_and_png_data_uri():
|
||||
tensor = torch.tensor(
|
||||
[[[[0.0, 0.5, 1.0], [1.0, float("nan"), 0.0]]]],
|
||||
dtype=torch.float32,
|
||||
)
|
||||
images = tensor_batch_to_pil(tensor)
|
||||
assert images[0].size == (2, 1)
|
||||
uri = image_data_uri(images[0])
|
||||
payload = base64.b64decode(uri.split(",", 1)[1])
|
||||
assert Image.open(io.BytesIO(payload)).format == "PNG"
|
||||
assert pil_to_tensor(images[0]).shape == (1, 1, 2, 3)
|
||||
assert pil_mask_to_tensor(Image.new("L", (2, 3))).shape == (1, 3, 2)
|
||||
|
||||
|
||||
def test_paligemma_parser_uses_normalized_boxes_and_16_codes():
|
||||
codes = "".join(f"<seg{index:03d}>" for index in range(16))
|
||||
parsed = paligemma.parse_segments(
|
||||
f"<loc0100><loc0200><loc0900><loc0800>{codes} cat"
|
||||
)
|
||||
assert len(parsed) == 1
|
||||
box, values, label = parsed[0]
|
||||
assert box == pytest.approx((100 / 1024, 200 / 1024, 900 / 1024, 800 / 1024))
|
||||
assert values == list(range(16))
|
||||
assert label == "cat"
|
||||
|
||||
|
||||
def test_florence_rendering_supports_boxes_quads_and_nested_polygons():
|
||||
image = Image.new("RGB", (32, 24), "black")
|
||||
parsed = {
|
||||
"<TASK>": {
|
||||
"bboxes": [[1, 1, 10, 10]],
|
||||
"labels": ["box"],
|
||||
"quad_boxes": [[2, 2, 8, 2, 8, 8, 2, 8]],
|
||||
"polygons": [[[4, 4, 20, 4, 20, 20, 4, 20]]],
|
||||
}
|
||||
}
|
||||
mask, visual = florence2._visualize(image, parsed)
|
||||
assert np.asarray(mask).max() == 255
|
||||
assert visual.size == image.size
|
||||
|
||||
|
||||
def test_modern_catalog_has_current_quality_and_low_vram_tiers():
|
||||
repositories = {spec.repo_id for spec in modern_vlm.MODEL_CATALOG.values()}
|
||||
small_fast = [spec for spec in modern_vlm.MODEL_CATALOG.values() if spec.small_fast]
|
||||
assert 10 <= len(small_fast) <= 20
|
||||
assert all(
|
||||
not spec.trust_remote_code
|
||||
for spec in modern_vlm.MODEL_CATALOG.values()
|
||||
if spec.family != "Custom"
|
||||
)
|
||||
assert modern_vlm.MODEL_CATALOG["Custom Hugging Face model"].trust_remote_code
|
||||
assert "Qwen/Qwen3.5-4B" in repositories
|
||||
assert "Qwen/Qwen3.5-35B-A3B" in repositories
|
||||
assert "Qwen/Qwen3.6-27B" in repositories
|
||||
assert "Qwen/Qwen3-VL-8B-Instruct" in repositories
|
||||
assert "Qwen/Qwen2.5-VL-3B-Instruct" in repositories
|
||||
assert "google/gemma-3-4b-it" in repositories
|
||||
assert "HuggingFaceTB/SmolVLM2-256M-Video-Instruct" in repositories
|
||||
assert "HuggingFaceTB/SmolVLM2-500M-Video-Instruct" in repositories
|
||||
assert "LiquidAI/LFM2.5-VL-450M" in repositories
|
||||
assert "LiquidAI/LFM2.5-VL-1.6B" in repositories
|
||||
assert "OpenGVLab/InternVL3_5-1B-HF" in repositories
|
||||
assert "OpenGVLab/InternVL3_5-2B-HF" in repositories
|
||||
assert "ibm-granite/granite-vision-3.3-2b" in repositories
|
||||
assert "ibm-granite/granite-vision-4.1-4b" in repositories
|
||||
|
||||
|
||||
def test_modern_picker_is_curated_and_legacy_models_remain_compatible():
|
||||
visible = tuple(modern_vlm.ModernVLM.INPUT_TYPES()["required"]["model"][0])
|
||||
legacy = tuple(
|
||||
modern_vlm.LegacyModernVLM.INPUT_TYPES()["required"]["model"][0]
|
||||
)
|
||||
assert visible == modern_vlm.RECOMMENDED_MODEL_LABELS
|
||||
assert legacy == modern_vlm.LEGACY_MODEL_LABELS
|
||||
assert len(visible) == 12
|
||||
assert set(visible).isdisjoint(legacy)
|
||||
assert set(visible) | set(legacy) == set(modern_vlm.MODEL_CATALOG)
|
||||
assert (
|
||||
modern_vlm.ModernVLM.VALIDATE_INPUTS(
|
||||
"Qwen 2.5 VL 3B Instruct (legacy workflows)"
|
||||
)
|
||||
is True
|
||||
)
|
||||
for node_name in (
|
||||
"Kosmos2model",
|
||||
"MCLLaVAModel",
|
||||
"MiniCPMNode",
|
||||
"MolmoNode",
|
||||
"MoonDream",
|
||||
"Paligemma",
|
||||
"Qwen2VLNode",
|
||||
"UformGen2QwenNode",
|
||||
):
|
||||
assert package.NODE_CLASS_MAPPINGS[node_name].CATEGORY.startswith(
|
||||
"VLM Nodes/Legacy/"
|
||||
)
|
||||
|
||||
|
||||
def test_modern_video_is_primary_input_and_thinking_is_explicit():
|
||||
assert "image" in modern_vlm.ModernVLM.INPUT_TYPES()["optional"]
|
||||
assert "image" in qwen2vl.Qwen2VLNode.INPUT_TYPES()["optional"]
|
||||
predictor = modern_vlm.ModernVLMPredictor.__new__(modern_vlm.ModernVLMPredictor)
|
||||
predictor.spec = modern_vlm.ModelSpec("test/model", "Qwen 3.5", 1.0, video=True)
|
||||
captured = {}
|
||||
|
||||
def capture(messages, enable_thinking=False, **kwargs):
|
||||
captured["messages"] = messages
|
||||
captured["enable_thinking"] = enable_thinking
|
||||
captured.update(kwargs)
|
||||
raise RuntimeError("captured before inference")
|
||||
|
||||
predictor._inputs = capture
|
||||
frames = torch.zeros((4, 8, 8, 3), dtype=torch.float32)
|
||||
with pytest.raises(RuntimeError, match="captured before inference"):
|
||||
predictor.generate(
|
||||
None,
|
||||
"What moves?",
|
||||
"",
|
||||
8,
|
||||
0.0,
|
||||
0.9,
|
||||
frames,
|
||||
2.0,
|
||||
True,
|
||||
)
|
||||
|
||||
content = captured["messages"][-1]["content"]
|
||||
assert [part["type"] for part in content] == ["video", "text"]
|
||||
assert len(content[0]["video"]) == 4
|
||||
assert "2 FPS" in content[1]["text"]
|
||||
assert captured["enable_thinking"] is True
|
||||
assert captured["video_metadata"]["fps"] == 2.0
|
||||
assert captured["video_metadata"]["frames_indices"] == [0, 1, 2, 3]
|
||||
|
||||
|
||||
def test_modern_vlm_streams_cumulative_text_without_changing_final_output(
|
||||
monkeypatch,
|
||||
):
|
||||
class FakeStreamer:
|
||||
def __init__(self, _tokenizer, **kwargs):
|
||||
assert kwargs["skip_prompt"] is True
|
||||
self.chunks = ["Hello ", "from ", "the VLM."]
|
||||
|
||||
def __iter__(self):
|
||||
return iter(self.chunks)
|
||||
|
||||
def end(self):
|
||||
pass
|
||||
|
||||
class FakeModel:
|
||||
def generate(self, **kwargs):
|
||||
assert isinstance(kwargs["streamer"], FakeStreamer)
|
||||
return torch.tensor([[10, 11, 12]], dtype=torch.long)
|
||||
|
||||
class FakeProcessor:
|
||||
tokenizer = object()
|
||||
|
||||
def batch_decode(self, *_args, **_kwargs):
|
||||
return ["fallback"]
|
||||
|
||||
predictor = modern_vlm.ModernVLMPredictor.__new__(
|
||||
modern_vlm.ModernVLMPredictor
|
||||
)
|
||||
predictor.spec = modern_vlm.ModelSpec("test/model", "Test", 1.0)
|
||||
predictor.dtype = torch.float32
|
||||
predictor.processor = FakeProcessor()
|
||||
predictor.streamer_class = FakeStreamer
|
||||
predictor.handle = SimpleNamespace(ensure_loaded=lambda: FakeModel())
|
||||
predictor._inputs = lambda *_args, **_kwargs: {
|
||||
"input_ids": torch.tensor([[1, 2]], dtype=torch.long)
|
||||
}
|
||||
|
||||
monkeypatch.setattr(modern_vlm, "model_device", lambda _model: torch.device("cpu"))
|
||||
monkeypatch.setattr(modern_vlm, "move_inputs", lambda inputs, _device: inputs)
|
||||
monkeypatch.setattr(
|
||||
modern_vlm,
|
||||
"inference_context",
|
||||
lambda *_args: nullcontext(),
|
||||
)
|
||||
partials = []
|
||||
result = predictor.generate(
|
||||
torch.zeros((1, 8, 8, 3), dtype=torch.float32),
|
||||
"Describe it.",
|
||||
"",
|
||||
16,
|
||||
0.0,
|
||||
0.9,
|
||||
stream_callback=partials.append,
|
||||
)
|
||||
|
||||
assert result == "Hello from the VLM."
|
||||
assert partials == ["Hello", "Hello from", "Hello from the VLM."]
|
||||
|
||||
|
||||
def test_view_text_frontend_rehydrates_and_uses_native_progress_channel():
|
||||
source = (
|
||||
Path(package.__file__).parent / "web" / "js" / "viewText.js"
|
||||
).read_text(encoding="utf-8")
|
||||
assert 'api.addEventListener("progress_text"' in source
|
||||
assert "onNodeOutputsUpdated(nodeOutputs)" in source
|
||||
assert "connectedViewTextNodes(source)" in source
|
||||
assert '"VLMVideoTemporalReasoner"' in source
|
||||
assert 'makeButton("Save"' in source
|
||||
assert 'makeButton("Wrap: on"' in source
|
||||
assert 'makeButton("Follow: on"' in source
|
||||
assert "isReroute(target)" in source
|
||||
|
||||
|
||||
def test_internvl_video_uses_an_even_vision_patch_grid():
|
||||
predictor = modern_vlm.ModernVLMPredictor.__new__(modern_vlm.ModernVLMPredictor)
|
||||
predictor.spec = modern_vlm.ModelSpec("test/model", "InternVL 3.5", 1.0, video=True)
|
||||
captured = {}
|
||||
|
||||
class ImageProcessor:
|
||||
size = {"height": 448, "width": 448}
|
||||
|
||||
class Processor:
|
||||
image_processor = ImageProcessor()
|
||||
|
||||
def apply_chat_template(self, _messages, **kwargs):
|
||||
captured.update(kwargs)
|
||||
return {"input_ids": torch.ones((1, 1), dtype=torch.long)}
|
||||
|
||||
predictor.processor = Processor()
|
||||
predictor._inputs(
|
||||
[{"role": "user", "content": [{"type": "text", "text": "test"}]}],
|
||||
video_metadata={"fps": 2.0},
|
||||
)
|
||||
assert captured["processor_kwargs"]["size"] == {
|
||||
"height": 448,
|
||||
"width": 448,
|
||||
}
|
||||
|
||||
|
||||
def test_qwen2_legacy_quantized_labels_use_maintained_backends():
|
||||
assert list(qwen2vl.QWEN2_VL_CHOICES) == [
|
||||
"Qwen2-VL-2B",
|
||||
"Qwen2-VL-7B",
|
||||
]
|
||||
assert qwen2vl.LEGACY_QUANTIZED_ALIASES["Qwen2-VL-7B-GPTQ-Int8"] == (
|
||||
"Qwen2-VL-7B",
|
||||
"Balanced (8-bit)",
|
||||
)
|
||||
assert qwen2vl.LEGACY_QUANTIZED_ALIASES["Qwen2-VL-7B-AWQ"] == (
|
||||
"Qwen2-VL-7B",
|
||||
"Maximum Savings (4-bit)",
|
||||
)
|
||||
|
||||
|
||||
def test_audioldm_keeps_legacy_outputs_and_adds_standard_audio(monkeypatch):
|
||||
class FakePredictor:
|
||||
def generate(self, *_args):
|
||||
return np.zeros((2, 16), dtype=np.float32), 16000
|
||||
|
||||
node = audioldm2.AudioLDM2Node()
|
||||
monkeypatch.setattr(node, "get_or_create_model", lambda *_args: FakePredictor())
|
||||
result = node.generate_audio_final("rain", "", 1, 3.5, 16000, 42, 2, "wav")
|
||||
assert len(result) == 3
|
||||
assert result[1] == 16000
|
||||
assert result[2]["waveform"].shape == (2, 1, 16)
|
||||
|
||||
|
||||
def test_node_functions_accept_every_declared_input_name():
|
||||
for node_class in package.NODE_CLASS_MAPPINGS.values():
|
||||
function = getattr(node_class, node_class.FUNCTION)
|
||||
signature = inspect.signature(function)
|
||||
if any(
|
||||
parameter.kind == inspect.Parameter.VAR_KEYWORD
|
||||
for parameter in signature.parameters.values()
|
||||
):
|
||||
continue
|
||||
declared = {
|
||||
name
|
||||
for group in node_class.INPUT_TYPES().values()
|
||||
if isinstance(group, dict)
|
||||
for name in group
|
||||
}
|
||||
accepted = set(signature.parameters)
|
||||
assert declared <= accepted, (
|
||||
node_class.__name__,
|
||||
declared - accepted,
|
||||
)
|
||||
@@ -0,0 +1,251 @@
|
||||
from types import SimpleNamespace
|
||||
|
||||
import pytest
|
||||
import torch
|
||||
from ComfyUI_VLM_nodes.nodes.sam2 import (
|
||||
SAM2_MODELS,
|
||||
Sam2Spec,
|
||||
Sam2VideoPredictor,
|
||||
VLMSAM2VideoSegmentation,
|
||||
_core_box,
|
||||
_normalize_processed_masks,
|
||||
seed_boxes,
|
||||
)
|
||||
from ComfyUI_VLM_nodes.nodes.vision_types import (
|
||||
Detection,
|
||||
DetectionSequence,
|
||||
FrameDetections,
|
||||
)
|
||||
|
||||
|
||||
def test_sam2_catalog_leads_with_tiny_and_has_no_30b_models():
|
||||
assert next(iter(SAM2_MODELS)) == "SAM2.1 Hiera Tiny (fast)"
|
||||
assert all("30b" not in spec.model_id.lower() for spec in SAM2_MODELS.values())
|
||||
assert VLMSAM2VideoSegmentation.RETURN_NAMES[0:2] == ("tracks", "json")
|
||||
|
||||
|
||||
def test_core_box_is_converted_from_xywh():
|
||||
assert _core_box({"x": 2, "y": 3, "width": 5, "height": 7}) == (
|
||||
2.0,
|
||||
3.0,
|
||||
7.0,
|
||||
10.0,
|
||||
)
|
||||
with pytest.raises(ValueError, match="positive"):
|
||||
_core_box({"x": 2, "y": 3, "width": 0, "height": 7})
|
||||
|
||||
|
||||
def test_detection_seeds_keep_labels_and_ids():
|
||||
detection = Detection(
|
||||
bbox_xyxy=(1, 2, 9, 10),
|
||||
label="cat",
|
||||
frame_index=2,
|
||||
timestamp=0.2,
|
||||
track_id=7,
|
||||
)
|
||||
sequence = DetectionSequence(
|
||||
width=10,
|
||||
height=10,
|
||||
frames=(
|
||||
FrameDetections(
|
||||
frame_index=2,
|
||||
timestamp=0.2,
|
||||
width=10,
|
||||
height=10,
|
||||
detections=(detection,),
|
||||
),
|
||||
),
|
||||
frame_count=3,
|
||||
fps=10,
|
||||
)
|
||||
boxes, ids, labels = seed_boxes(
|
||||
width=10,
|
||||
height=10,
|
||||
frame_index=2,
|
||||
detections=sequence,
|
||||
bounding_box=None,
|
||||
)
|
||||
assert boxes == [[1.0, 2.0, 9.0, 10.0]]
|
||||
assert ids == [7]
|
||||
assert labels == {7: "cat"}
|
||||
|
||||
|
||||
def test_processed_mask_shapes_are_normalized():
|
||||
assert _normalize_processed_masks(torch.zeros(2, 1, 4, 5)).shape == (
|
||||
2,
|
||||
4,
|
||||
5,
|
||||
)
|
||||
assert _normalize_processed_masks(torch.zeros(4, 5)).shape == (1, 4, 5)
|
||||
with pytest.raises(RuntimeError, match="unsupported"):
|
||||
_normalize_processed_masks(torch.zeros(1, 2, 3, 4, 5))
|
||||
|
||||
|
||||
def test_video_session_runs_seed_frame_before_both_propagation_directions():
|
||||
class FakeProcessor:
|
||||
def init_video_session(self, **_kwargs):
|
||||
return SimpleNamespace(obj_ids=[1], seed_inferred=False)
|
||||
|
||||
def add_inputs_to_inference_session(self, **kwargs):
|
||||
kwargs["inference_session"].seed_frame = kwargs["frame_idx"]
|
||||
|
||||
def post_process_masks(self, masks, **_kwargs):
|
||||
return masks
|
||||
|
||||
class FakeModel(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.anchor = torch.nn.Parameter(torch.zeros(()))
|
||||
self.seed_calls = []
|
||||
self.propagation_directions = []
|
||||
|
||||
def forward(self, inference_session, frame_idx):
|
||||
inference_session.seed_inferred = True
|
||||
self.seed_calls.append(frame_idx)
|
||||
return SimpleNamespace(
|
||||
frame_idx=frame_idx,
|
||||
pred_masks=torch.ones(1, 1, 4, 4),
|
||||
)
|
||||
|
||||
def propagate_in_video_iterator(
|
||||
self,
|
||||
inference_session,
|
||||
start_frame_idx,
|
||||
reverse=False,
|
||||
**_kwargs,
|
||||
):
|
||||
assert inference_session.seed_inferred
|
||||
self.propagation_directions.append(reverse)
|
||||
indices = (
|
||||
range(start_frame_idx, 3)
|
||||
if not reverse
|
||||
else range(start_frame_idx, -1, -1)
|
||||
)
|
||||
for frame_index in indices:
|
||||
yield SimpleNamespace(
|
||||
frame_idx=frame_index,
|
||||
pred_masks=torch.ones(1, 1, 4, 4),
|
||||
)
|
||||
|
||||
model = FakeModel()
|
||||
predictor = Sam2VideoPredictor.__new__(Sam2VideoPredictor)
|
||||
predictor.processor = FakeProcessor()
|
||||
predictor.dtype = torch.float32
|
||||
predictor.spec = Sam2Spec("test/sam2", "test-sam2")
|
||||
predictor.handle = SimpleNamespace(ensure_loaded=lambda: model)
|
||||
detections = DetectionSequence(
|
||||
width=4,
|
||||
height=4,
|
||||
frames=(
|
||||
FrameDetections(
|
||||
frame_index=0,
|
||||
timestamp=0.0,
|
||||
width=4,
|
||||
height=4,
|
||||
detections=(
|
||||
Detection(
|
||||
bbox_xyxy=(0, 0, 4, 4),
|
||||
label="object",
|
||||
frame_index=0,
|
||||
timestamp=0.0,
|
||||
),
|
||||
),
|
||||
),
|
||||
),
|
||||
frame_count=1,
|
||||
)
|
||||
tracks, union, individual, preview = predictor.propagate(
|
||||
torch.zeros(3, 4, 4, 3),
|
||||
seed_frame=1,
|
||||
fps=10.0,
|
||||
detections=detections,
|
||||
bounding_box=None,
|
||||
seed_mask=None,
|
||||
mask_threshold=0.0,
|
||||
keep_video_on_cpu=True,
|
||||
mask_output="union_and_objects",
|
||||
render_preview=True,
|
||||
)
|
||||
assert model.seed_calls == [1]
|
||||
assert model.propagation_directions == [False, True]
|
||||
assert [item.frame_index for item in tracks.tracks[0].detections] == [0, 1, 2]
|
||||
assert union.shape == (3, 4, 4)
|
||||
assert individual.shape == (3, 4, 4)
|
||||
assert preview.shape == (3, 4, 4, 3)
|
||||
assert torch.equal(preview[0], preview[1])
|
||||
assert torch.equal(preview[1], preview[2])
|
||||
|
||||
|
||||
def test_multi_object_mask_seeds_are_passed_as_one_mask_per_object():
|
||||
class FakeProcessor:
|
||||
def __init__(self):
|
||||
self.received_masks = None
|
||||
|
||||
def init_video_session(self, **kwargs):
|
||||
assert str(kwargs["processing_device"]) == "cpu"
|
||||
return SimpleNamespace(obj_ids=[1, 2], seed_inferred=False)
|
||||
|
||||
def add_inputs_to_inference_session(self, **kwargs):
|
||||
self.received_masks = kwargs["input_masks"]
|
||||
|
||||
def post_process_masks(self, masks, **_kwargs):
|
||||
return masks
|
||||
|
||||
class FakeModel(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.anchor = torch.nn.Parameter(torch.zeros(()))
|
||||
|
||||
def forward(self, inference_session, frame_idx):
|
||||
inference_session.seed_inferred = True
|
||||
return SimpleNamespace(
|
||||
frame_idx=frame_idx,
|
||||
pred_masks=torch.ones(2, 1, 4, 4),
|
||||
)
|
||||
|
||||
def propagate_in_video_iterator(self, **_kwargs):
|
||||
return iter(())
|
||||
|
||||
processor = FakeProcessor()
|
||||
predictor = Sam2VideoPredictor.__new__(Sam2VideoPredictor)
|
||||
predictor.processor = processor
|
||||
predictor.dtype = torch.float32
|
||||
predictor.spec = Sam2Spec("test/sam2", "test-sam2")
|
||||
predictor.handle = SimpleNamespace(ensure_loaded=FakeModel)
|
||||
images = torch.zeros(1, 4, 4, 3)
|
||||
tracks, _union, individual, preview = predictor.propagate(
|
||||
images,
|
||||
seed_frame=0,
|
||||
fps=24.0,
|
||||
detections=None,
|
||||
bounding_box=None,
|
||||
seed_mask=torch.ones(2, 4, 4),
|
||||
mask_threshold=0.0,
|
||||
keep_video_on_cpu=True,
|
||||
mask_output="union_only",
|
||||
render_preview=False,
|
||||
)
|
||||
assert isinstance(processor.received_masks, list)
|
||||
assert len(processor.received_masks) == 2
|
||||
assert len(tracks.tracks) == 2
|
||||
assert individual.shape == (0, 4, 4)
|
||||
assert preview.data_ptr() == images.data_ptr()
|
||||
|
||||
|
||||
def test_nested_core_boxes_select_seed_frame_and_keep_top_level_labels():
|
||||
boxes, ids, labels = seed_boxes(
|
||||
width=20,
|
||||
height=20,
|
||||
frame_index=1,
|
||||
detections=None,
|
||||
bounding_box=[
|
||||
[{"x": 0, "y": 0, "width": 2, "height": 2, "label": "old"}],
|
||||
[
|
||||
{"x": 3, "y": 4, "width": 5, "height": 6, "label": "person"},
|
||||
{"x": 10, "y": 11, "width": 4, "height": 3},
|
||||
],
|
||||
],
|
||||
)
|
||||
assert boxes == [[3.0, 4.0, 8.0, 10.0], [10.0, 11.0, 14.0, 14.0]]
|
||||
assert ids == [1, 2]
|
||||
assert labels == {1: "person", 2: None}
|
||||
@@ -0,0 +1,213 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
|
||||
import pytest
|
||||
import torch
|
||||
from ComfyUI_VLM_nodes.nodes.sam3_adapter import (
|
||||
VLMTrackReport,
|
||||
iter_sam3_masks,
|
||||
sam3_track_data_to_tracks,
|
||||
track_report_json,
|
||||
track_report_payload,
|
||||
track_report_text,
|
||||
unpack_sam3_mask,
|
||||
validate_sam3_track_data,
|
||||
)
|
||||
from ComfyUI_VLM_nodes.nodes.vision_types import (
|
||||
Detection,
|
||||
DetectionSequence,
|
||||
FrameDetections,
|
||||
)
|
||||
|
||||
|
||||
def _pack_masks(masks):
|
||||
masks = masks.to(torch.uint8)
|
||||
width = masks.shape[-1]
|
||||
assert width % 8 == 0
|
||||
bits = 1 << torch.arange(8, dtype=torch.int64)
|
||||
grouped = masks.reshape(*masks.shape[:-1], width // 8, 8)
|
||||
return (grouped * bits).sum(dim=-1).to(torch.uint8)
|
||||
|
||||
|
||||
def _sample_track_data():
|
||||
masks = torch.zeros(2, 2, 4, 8, dtype=torch.bool)
|
||||
masks[0, 0, 1:3, 2:5] = True
|
||||
masks[1, 0, 1:4, 3:6] = True
|
||||
masks[1, 1, 0:2, 0:2] = True
|
||||
return {
|
||||
"packed_masks": _pack_masks(masks),
|
||||
"n_frames": 2,
|
||||
"scores": [0.9, 0.75],
|
||||
"orig_size": (40, 80),
|
||||
}
|
||||
|
||||
|
||||
def _seed_detections():
|
||||
detections = (
|
||||
Detection(
|
||||
bbox_xyxy=(20, 10, 50, 30),
|
||||
label="cat",
|
||||
text="the cat",
|
||||
score=0.95,
|
||||
frame_index=0,
|
||||
timestamp=0.0,
|
||||
track_id=7,
|
||||
source="seed",
|
||||
),
|
||||
Detection(
|
||||
bbox_xyxy=(0, 0, 20, 20),
|
||||
label="fish",
|
||||
score=0.8,
|
||||
frame_index=0,
|
||||
timestamp=0.0,
|
||||
track_id=9,
|
||||
source="seed",
|
||||
),
|
||||
)
|
||||
return DetectionSequence(
|
||||
width=80,
|
||||
height=40,
|
||||
frames=(
|
||||
FrameDetections(
|
||||
frame_index=0,
|
||||
timestamp=0.0,
|
||||
width=80,
|
||||
height=40,
|
||||
detections=detections,
|
||||
),
|
||||
),
|
||||
frame_count=2,
|
||||
fps=10.0,
|
||||
)
|
||||
|
||||
|
||||
def test_validate_and_stream_unpack_without_expanding_the_video():
|
||||
track_data = _sample_track_data()
|
||||
layout = validate_sam3_track_data(track_data)
|
||||
assert (
|
||||
layout.n_frames,
|
||||
layout.n_objects,
|
||||
layout.mask_height,
|
||||
layout.mask_width,
|
||||
) == (2, 2, 4, 8)
|
||||
yielded = list(iter_sam3_masks(track_data, present_only=True))
|
||||
assert [(frame, obj) for frame, obj, _mask in yielded] == [
|
||||
(0, 0),
|
||||
(1, 0),
|
||||
(1, 1),
|
||||
]
|
||||
assert all(mask.shape == (4, 8) for _frame, _obj, mask in yielded)
|
||||
assert yielded[0][2].sum().item() == 6
|
||||
one = unpack_sam3_mask(track_data["packed_masks"][1, 1])
|
||||
assert one.dtype == torch.bool
|
||||
assert one.sum().item() == 4
|
||||
|
||||
|
||||
def test_adapter_derives_scaled_boxes_and_preserves_seed_identity():
|
||||
tracks = sam3_track_data_to_tracks(
|
||||
_sample_track_data(),
|
||||
seed_detections=_seed_detections(),
|
||||
fps=10.0,
|
||||
)
|
||||
assert (tracks.width, tracks.height, tracks.frame_count, tracks.fps) == (
|
||||
80,
|
||||
40,
|
||||
2,
|
||||
10.0,
|
||||
)
|
||||
assert [track.track_id for track in tracks.tracks] == [7, 9]
|
||||
assert [track.label for track in tracks.tracks] == ["cat", "fish"]
|
||||
cat, fish = tracks.tracks
|
||||
assert cat.detections[0].bbox_xyxy == (20.0, 10.0, 50.0, 30.0)
|
||||
assert cat.detections[1].bbox_xyxy == (30.0, 10.0, 60.0, 40.0)
|
||||
assert fish.detections[0].frame_index == 1
|
||||
assert fish.detections[0].bbox_xyxy == (0.0, 0.0, 20.0, 20.0)
|
||||
assert cat.detections[0].metadata["mask_ref"]["object_index"] == 0
|
||||
assert fish.detections[0].metadata["mask_ref"]["object_index"] == 1
|
||||
assert cat.metadata["seeded"] is True
|
||||
assert fish.metadata["seeded"] is True
|
||||
|
||||
serialized = tracks.to_json()
|
||||
assert "mask_ref" in serialized
|
||||
assert "packed_masks" not in serialized
|
||||
assert "tensor" not in serialized.casefold()
|
||||
|
||||
|
||||
def test_adapter_handles_an_empty_core_result():
|
||||
tracks = sam3_track_data_to_tracks(
|
||||
{
|
||||
"packed_masks": None,
|
||||
"n_frames": 3,
|
||||
"scores": [],
|
||||
"orig_size": (48, 64),
|
||||
},
|
||||
fps=24.0,
|
||||
)
|
||||
assert tracks.tracks == ()
|
||||
assert tracks.frame_count == 3
|
||||
assert tracks.metadata["object_slots"] == 0
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("track_data", "message"),
|
||||
(
|
||||
(
|
||||
{"packed_masks": None, "n_frames": 1, "scores": []},
|
||||
"orig_size",
|
||||
),
|
||||
(
|
||||
{
|
||||
"packed_masks": torch.zeros(1, 1, 2, 1),
|
||||
"n_frames": 1,
|
||||
"scores": [0.5],
|
||||
"orig_size": (2, 8),
|
||||
},
|
||||
"uint8",
|
||||
),
|
||||
(
|
||||
{
|
||||
"packed_masks": torch.zeros(2, 1, 2, 1, dtype=torch.uint8),
|
||||
"n_frames": 1,
|
||||
"scores": [0.5],
|
||||
"orig_size": (2, 8),
|
||||
},
|
||||
"n_frames",
|
||||
),
|
||||
(
|
||||
{
|
||||
"packed_masks": torch.zeros(1, 1, 2, 1, dtype=torch.uint8),
|
||||
"n_frames": 1,
|
||||
"scores": [1.5],
|
||||
"orig_size": (2, 8),
|
||||
},
|
||||
"0 to 1",
|
||||
),
|
||||
),
|
||||
)
|
||||
def test_adapter_rejects_incompatible_private_payloads(track_data, message):
|
||||
with pytest.raises((TypeError, ValueError), match=message):
|
||||
validate_sam3_track_data(track_data)
|
||||
|
||||
|
||||
def test_track_report_is_small_deterministic_and_history_safe():
|
||||
tracks = sam3_track_data_to_tracks(
|
||||
_sample_track_data(),
|
||||
seed_detections=_seed_detections(),
|
||||
fps=10.0,
|
||||
)
|
||||
payload = track_report_payload(tracks)
|
||||
assert payload["track_count"] == 2
|
||||
assert payload["observation_count"] == 3
|
||||
assert payload["state_counts"] == {"active": 2}
|
||||
encoded = track_report_json(tracks)
|
||||
assert json.loads(encoded) == payload
|
||||
assert "packed_masks" not in encoded
|
||||
text = track_report_text(tracks)
|
||||
assert "Tracks: 2" in text
|
||||
assert "#7 cat" in text
|
||||
assert "#9 fish" in text
|
||||
|
||||
node_result = VLMTrackReport().report(tracks)
|
||||
assert node_result["result"] == (encoded, text)
|
||||
assert node_result["ui"]["text"] == [text]
|
||||
@@ -0,0 +1,212 @@
|
||||
import json
|
||||
from pathlib import Path
|
||||
|
||||
import pytest
|
||||
|
||||
import ComfyUI_VLM_nodes as package
|
||||
from ComfyUI_VLM_nodes.nodes import simpletext
|
||||
|
||||
|
||||
def test_simple_text_preserves_legacy_default_and_appends_metrics():
|
||||
result = simpletext.SimpleText().simple_text(" one\r\ntwo ")
|
||||
assert result == (" one\r\ntwo ", 12, 2, 2)
|
||||
|
||||
normalized = simpletext.SimpleText().simple_text(
|
||||
" one\r\ntwo ",
|
||||
trim_edges=True,
|
||||
normalize_newlines=True,
|
||||
)
|
||||
assert normalized == ("one\ntwo", 7, 2, 2)
|
||||
|
||||
|
||||
def test_json_to_text_keeps_legacy_smart_rendering_and_adds_canonical_output():
|
||||
response = simpletext.JsonToText().json_to_text(
|
||||
'{"prompt":"Create a red kite","suggestion1":"at sunset","tags":["red","sky"]}'
|
||||
)
|
||||
assert response["result"][0] == "a red kite\n\nat sunset\n\ntags: red, sky"
|
||||
assert json.loads(response["result"][1])["tags"] == ["red", "sky"]
|
||||
assert response["result"][2] == 3
|
||||
|
||||
|
||||
def test_json_to_text_parses_fenced_model_response_and_json_paths():
|
||||
response = simpletext.JsonToText().json_to_text(
|
||||
'Model response:\n```json\n{"result":{"items":[{"name":"café"}]}}\n```',
|
||||
format_mode="Pretty JSON",
|
||||
json_path="$.result.items[0]",
|
||||
)
|
||||
assert json.loads(response["result"][0]) == {"name": "café"}
|
||||
assert response["result"][1] == '{"name":"café"}'
|
||||
|
||||
pointer = simpletext.VLMJSONExtract().extract(
|
||||
'{"a/b":{"~key":[10,20]}}',
|
||||
"/a~1b/~0key/1",
|
||||
"Text",
|
||||
"Error",
|
||||
"",
|
||||
)
|
||||
assert pointer == ("20", True, "integer", "20")
|
||||
|
||||
|
||||
def test_json_extract_handles_negative_indexes_and_missing_policy():
|
||||
node = simpletext.VLMJSONExtract()
|
||||
assert node.extract(
|
||||
'{"items":["first","last"]}',
|
||||
"$.items[-1]",
|
||||
"Text",
|
||||
"Error",
|
||||
"",
|
||||
)[:3] == ("last", True, "string")
|
||||
assert node.extract(
|
||||
'{"items":[]}',
|
||||
"$.missing",
|
||||
"Text",
|
||||
"Default value",
|
||||
"fallback",
|
||||
)[:3] == ("fallback", False, "string")
|
||||
with pytest.raises(ValueError, match="not found"):
|
||||
node.extract("{}", "$.missing", "Text", "Error", "")
|
||||
|
||||
|
||||
def test_text_join_drops_empty_and_duplicate_parts():
|
||||
result = simpletext.VLMTextJoin().join(
|
||||
" first ",
|
||||
"Blank line",
|
||||
"|",
|
||||
True,
|
||||
True,
|
||||
True,
|
||||
text_b="second",
|
||||
text_c="first",
|
||||
)
|
||||
assert result == (
|
||||
"first\n\nsecond",
|
||||
'["first","second"]',
|
||||
2,
|
||||
)
|
||||
|
||||
|
||||
def test_text_template_is_safe_explicit_and_supports_literal_braces():
|
||||
result = simpletext.VLMTextTemplate().render(
|
||||
"{{schema}} {subject}: {text1}",
|
||||
'{"subject":"robot"}',
|
||||
"Error",
|
||||
text1="moving a box",
|
||||
)
|
||||
assert result[0] == "{schema} robot: moving a box"
|
||||
assert json.loads(result[1]) == {
|
||||
"subject": "robot",
|
||||
"text1": "moving a box",
|
||||
}
|
||||
assert result[2] == "[]"
|
||||
|
||||
with pytest.raises(ValueError, match="missing"):
|
||||
simpletext.VLMTextTemplate().render(
|
||||
"{known} {unknown}",
|
||||
'{"known":"yes"}',
|
||||
"Error",
|
||||
)
|
||||
|
||||
|
||||
def test_text_clean_normalizes_fences_duplicates_and_length():
|
||||
result, diagnostics_json = simpletext.VLMTextClean().clean(
|
||||
"```text\r\nA B\r\nA B\r\nC\r\n```",
|
||||
"NFKC",
|
||||
"Collapse horizontal",
|
||||
True,
|
||||
True,
|
||||
True,
|
||||
5,
|
||||
)
|
||||
assert result == "A B\nC"
|
||||
diagnostics = json.loads(diagnostics_json)
|
||||
assert diagnostics["changed"] is True
|
||||
assert diagnostics["duplicate_lines_removed"] == 1
|
||||
assert diagnostics["truncated"] is False
|
||||
|
||||
|
||||
def test_text_replace_literal_regex_and_errors():
|
||||
node = simpletext.VLMTextReplace()
|
||||
assert node.replace(
|
||||
"Cat cat cat",
|
||||
"cat",
|
||||
"dog",
|
||||
"Literal",
|
||||
False,
|
||||
2,
|
||||
"Keep text",
|
||||
)[:2] == ("dog dog cat", 2)
|
||||
assert node.replace(
|
||||
"a1 b22",
|
||||
r"\d+",
|
||||
"#",
|
||||
"Regular expression",
|
||||
True,
|
||||
0,
|
||||
"Keep text",
|
||||
)[:2] == ("a# b#", 2)
|
||||
with pytest.raises(ValueError, match="not found"):
|
||||
node.replace("hello", "x", "y", "Literal", True, 0, "Error")
|
||||
|
||||
|
||||
def test_text_split_outputs_real_list_and_stable_json():
|
||||
items, items_json, count = simpletext.VLMTextSplit().split(
|
||||
'[" first ","second","first",""]',
|
||||
"JSON array",
|
||||
",",
|
||||
True,
|
||||
True,
|
||||
True,
|
||||
0,
|
||||
)
|
||||
assert items == ["first", "second"]
|
||||
assert json.loads(items_json) == items
|
||||
assert count == 2
|
||||
assert simpletext.VLMTextSplit.OUTPUT_IS_LIST == (True, False, False)
|
||||
|
||||
|
||||
def test_text_inspector_and_view_text_report_same_metrics():
|
||||
inspected = simpletext.VLMTextInspect().inspect("hello\nworld")
|
||||
assert inspected[1:6] == (11, 11, 2, 2, 3)
|
||||
assert len(inspected[6]) == 64
|
||||
assert json.loads(inspected[7])["words"] == 2
|
||||
|
||||
viewed = simpletext.ViewText().view_text("hello\nworld")
|
||||
assert viewed["result"][:4] == ("hello\nworld", 11, 2, 2)
|
||||
assert viewed["ui"]["text"] == ["hello\nworld"]
|
||||
|
||||
|
||||
def test_text_node_categories_aliases_and_legacy_ids_are_stable():
|
||||
assert simpletext.NODE_CLASS_MAPPINGS["SimpleText"] is simpletext.SimpleText
|
||||
assert simpletext.NODE_CLASS_MAPPINGS["JsonToText"] is simpletext.JsonToText
|
||||
assert simpletext.NODE_CLASS_MAPPINGS["ViewText"] is simpletext.ViewText
|
||||
assert set(simpletext.NODE_CLASS_MAPPINGS) == {
|
||||
"SimpleText",
|
||||
"JsonToText",
|
||||
"ViewText",
|
||||
"VLMTextJoin",
|
||||
"VLMTextTemplate",
|
||||
"VLMTextClean",
|
||||
"VLMTextReplace",
|
||||
"VLMJSONExtract",
|
||||
"VLMTextSplit",
|
||||
"VLMTextInspect",
|
||||
}
|
||||
assert simpletext.SimpleText.CATEGORY == "VLM Nodes/Text/Create"
|
||||
assert simpletext.ViewText.CATEGORY == "VLM Nodes/Text/Inspect"
|
||||
|
||||
|
||||
def test_text_toolkit_api_example_uses_registered_inputs_and_output_indexes():
|
||||
root = Path(package.__file__).parent
|
||||
prompt = json.loads(
|
||||
(root / "examples" / "text_toolkit_api.json").read_text("utf-8")
|
||||
)
|
||||
assert prompt["5"]["inputs"]["text"] == ["4", 0]
|
||||
for node in prompt.values():
|
||||
node_class = package.NODE_CLASS_MAPPINGS[node["class_type"]]
|
||||
declared = {
|
||||
name
|
||||
for group in node_class.INPUT_TYPES().values()
|
||||
if isinstance(group, dict)
|
||||
for name in group
|
||||
}
|
||||
assert set(node["inputs"]) <= declared
|
||||
@@ -0,0 +1,376 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
|
||||
import pytest
|
||||
from ComfyUI_VLM_nodes.nodes.spatial_parser import (
|
||||
COORDINATE_MODES,
|
||||
VLMSpatialPromptBuilder,
|
||||
VLMStructuredSpatialParser,
|
||||
build_spatial_prompt,
|
||||
load_json_document,
|
||||
parse_spatial_response,
|
||||
)
|
||||
from ComfyUI_VLM_nodes.nodes.vision_types import (
|
||||
VLM_DETECTIONS,
|
||||
VLM_POINTS,
|
||||
DetectionSequence,
|
||||
PointSequence,
|
||||
)
|
||||
|
||||
|
||||
def test_prompt_builder_is_explicit_and_provider_neutral():
|
||||
prompt = build_spatial_prompt(
|
||||
"Find every vehicle.",
|
||||
coordinate_mode="normalized_0_1000",
|
||||
width=1920,
|
||||
height=1080,
|
||||
frame_count=12,
|
||||
fps=24.0,
|
||||
)
|
||||
|
||||
assert prompt.startswith("Perform this visual analysis task:")
|
||||
assert "Find every vehicle." in prompt
|
||||
assert "Return only one valid JSON object" in prompt
|
||||
assert "normalized_0_1000" in prompt
|
||||
assert '"frame_count":12' in prompt
|
||||
assert '"fps":24.0' in prompt
|
||||
assert "zero-based frame_index" in prompt
|
||||
assert "bbox_xyxy" in prompt
|
||||
assert "polygon" in prompt
|
||||
assert '"point"' in prompt
|
||||
assert "score" in prompt
|
||||
example = json.loads(prompt.split("Required JSON shape:\n", 1)[1])
|
||||
assert example["coordinate_mode"] == "normalized_0_1000"
|
||||
|
||||
|
||||
def test_node_contracts_use_canonical_spatial_types():
|
||||
assert tuple(COORDINATE_MODES) == (
|
||||
"pixel",
|
||||
"normalized_0_1",
|
||||
"normalized_0_1000",
|
||||
)
|
||||
assert VLMSpatialPromptBuilder.RETURN_TYPES == ("STRING",)
|
||||
assert VLMStructuredSpatialParser.RETURN_TYPES == (
|
||||
VLM_DETECTIONS,
|
||||
VLM_POINTS,
|
||||
"STRING",
|
||||
)
|
||||
schema = VLMStructuredSpatialParser.INPUT_TYPES()
|
||||
assert tuple(schema["required"]["coordinate_mode"][0]) == COORDINATE_MODES
|
||||
|
||||
|
||||
def test_parser_accepts_only_complete_plain_or_fenced_json():
|
||||
assert load_json_document(" ") == {}
|
||||
assert load_json_document('```json\n{"frames":[]}\n```') == {"frames": []}
|
||||
|
||||
for invalid in (
|
||||
'Here is the result: {"frames":[]}',
|
||||
'Result:\n```json\n{"frames":[]}\n```',
|
||||
'{"frames":[]} trailing',
|
||||
"```python\n{}\n```",
|
||||
'{"x": 1, "x": 2}',
|
||||
'{"score": NaN}',
|
||||
):
|
||||
with pytest.raises(ValueError):
|
||||
load_json_document(invalid)
|
||||
|
||||
|
||||
def test_normalized_video_parse_clips_and_preserves_metadata():
|
||||
response = json.dumps(
|
||||
{
|
||||
"coordinate_mode": "normalized_0_1",
|
||||
"media": {
|
||||
"width": 200,
|
||||
"height": 100,
|
||||
"frame_count": 3,
|
||||
"fps": 2,
|
||||
"codec": "test-codec",
|
||||
},
|
||||
"source": "unit-vlm",
|
||||
"metadata": {"request_id": "abc"},
|
||||
"vendor": {"latency_ms": 12},
|
||||
"frames": [
|
||||
{
|
||||
"frame_index": 0,
|
||||
"metadata": {"scene": "start"},
|
||||
"detections": [
|
||||
{
|
||||
"class": "cat",
|
||||
"confidence": 0.75,
|
||||
"bbox": [-0.1, 0.2, 1.2, 0.8],
|
||||
"polygon": [
|
||||
[-0.5, 0.2],
|
||||
[0.5, 0.2],
|
||||
[0.5, 1.5],
|
||||
],
|
||||
"instance_id": "cat-1",
|
||||
"metadata": {"occluded": False},
|
||||
}
|
||||
],
|
||||
"points": [
|
||||
{
|
||||
"name": "nose",
|
||||
"point": [0.25, 0.5],
|
||||
"confidence": 0.9,
|
||||
"landmark_id": 7,
|
||||
}
|
||||
],
|
||||
},
|
||||
{
|
||||
"frame_index": 2,
|
||||
"detections": [
|
||||
{
|
||||
"label": "sign",
|
||||
"quad": [
|
||||
[0.1, 0.1],
|
||||
[0.9, 0.1],
|
||||
[0.9, 0.9],
|
||||
[0.1, 0.9],
|
||||
],
|
||||
"text": "STOP",
|
||||
}
|
||||
],
|
||||
},
|
||||
],
|
||||
}
|
||||
)
|
||||
|
||||
detections, points, normalized_json = parse_spatial_response(
|
||||
f"```json\n{response}\n```",
|
||||
width=200,
|
||||
height=100,
|
||||
coordinate_mode="normalized_0_1",
|
||||
)
|
||||
|
||||
assert isinstance(detections, DetectionSequence)
|
||||
assert isinstance(points, PointSequence)
|
||||
assert detections.frame_count == points.frame_count == 3
|
||||
assert detections.fps == points.fps == 2.0
|
||||
assert [frame.frame_index for frame in detections.frames] == [0, 2]
|
||||
cat, sign = detections.all_detections()
|
||||
assert cat.bbox_xyxy == (0.0, 20.0, 200.0, 80.0)
|
||||
assert cat.polygon == ((0.0, 20.0), (100.0, 20.0), (100.0, 100.0))
|
||||
assert cat.label == "cat"
|
||||
assert cat.score == 0.75
|
||||
assert cat.metadata.to_dict() == {
|
||||
"instance_id": "cat-1",
|
||||
"occluded": False,
|
||||
}
|
||||
assert sign.bbox_xyxy == (20.0, 10.0, 180.0, 90.0)
|
||||
assert sign.quad is not None and len(sign.quad) == 4
|
||||
assert sign.text == "STOP"
|
||||
assert points.points[0].x == 50.0
|
||||
assert points.points[0].y == 50.0
|
||||
assert points.points[0].label == "nose"
|
||||
assert points.points[0].metadata["landmark_id"] == 7
|
||||
assert detections.frames[0].metadata["scene"] == "start"
|
||||
assert detections.metadata.to_dict() == {
|
||||
"coordinate_mode": "normalized_0_1",
|
||||
"media_metadata": {"codec": "test-codec"},
|
||||
"request_id": "abc",
|
||||
"vendor": {"latency_ms": 12},
|
||||
}
|
||||
|
||||
normalized = json.loads(normalized_json)
|
||||
assert normalized["schema"] == "comfyui-vlm/spatial"
|
||||
assert normalized["detections"] == detections.to_dict()
|
||||
assert normalized["points"] == points.to_dict()
|
||||
|
||||
|
||||
def test_pixel_aliases_xywh_flat_segmentation_and_multiple_points():
|
||||
response = json.dumps(
|
||||
{
|
||||
"objects": [
|
||||
{
|
||||
"name": "panel",
|
||||
"box": {"x": -2, "y": 5, "width": 15, "height": 30},
|
||||
"segmentation": [0, 5, 13, 5, 13, 35, 0, 35],
|
||||
"points": [[2, 7], [12, 30]],
|
||||
"score": 1,
|
||||
}
|
||||
]
|
||||
}
|
||||
)
|
||||
detections, points, _json = parse_spatial_response(
|
||||
response,
|
||||
width=10,
|
||||
height=20,
|
||||
coordinate_mode="pixel",
|
||||
frame_count=1,
|
||||
)
|
||||
|
||||
detection = detections.all_detections()[0]
|
||||
assert detection.bbox_xyxy == (0.0, 5.0, 10.0, 20.0)
|
||||
assert detection.polygon == (
|
||||
(0.0, 5.0),
|
||||
(10.0, 5.0),
|
||||
(10.0, 20.0),
|
||||
(0.0, 20.0),
|
||||
)
|
||||
assert [(point.x, point.y) for point in points.points] == [
|
||||
(2.0, 7.0),
|
||||
(10.0, 20.0),
|
||||
]
|
||||
|
||||
|
||||
def test_direct_multi_point_record_keeps_shared_fields_without_duplicates():
|
||||
detections, points, _json = parse_spatial_response(
|
||||
'{"label":"hand","confidence":0.8,"points":[[1,2],[3,4]],'
|
||||
'"metadata":{"side":"left"}}',
|
||||
width=10,
|
||||
height=10,
|
||||
)
|
||||
|
||||
assert detections.all_detections() == ()
|
||||
assert [(point.x, point.y) for point in points.points] == [
|
||||
(1.0, 2.0),
|
||||
(3.0, 4.0),
|
||||
]
|
||||
assert {point.label for point in points.points} == {"hand"}
|
||||
assert {point.score for point in points.points} == {0.8}
|
||||
assert points.points[0].metadata["side"] == "left"
|
||||
assert detections.frames[0].metadata.to_dict() == {}
|
||||
|
||||
|
||||
def test_top_level_record_batch_groups_video_frame_indices_and_timestamps():
|
||||
response = json.dumps(
|
||||
[
|
||||
{"frame_index": 2, "bbox_xyxy": [1, 2, 3, 4], "label": "late"},
|
||||
{"frame_index": 0, "point": [5, 6], "label": "early"},
|
||||
{"frame_index": 0, "box": [0, 0, 4, 5], "label": "first"},
|
||||
]
|
||||
)
|
||||
detections, points, _json = parse_spatial_response(
|
||||
response,
|
||||
width=20,
|
||||
height=10,
|
||||
fps=4,
|
||||
coordinate_mode="pixel",
|
||||
)
|
||||
|
||||
assert [frame.frame_index for frame in detections.frames] == [0, 2]
|
||||
assert detections.frames[1].timestamp == 0.5
|
||||
assert detections.frame_count == 3
|
||||
assert [item.label for item in detections.all_detections()] == [
|
||||
"first",
|
||||
"late",
|
||||
]
|
||||
assert points.points[0].frame_index == 0
|
||||
|
||||
|
||||
def test_normalized_1000_polygon_without_box_derives_clipped_bbox():
|
||||
detections, points, _json = parse_spatial_response(
|
||||
'{"polygon":[[-100,100],[500,100],[1200,900]],"label":"shape"}',
|
||||
width=300,
|
||||
height=200,
|
||||
coordinate_mode="normalized_0_1000",
|
||||
)
|
||||
|
||||
detection = detections.all_detections()[0]
|
||||
assert detection.bbox_xyxy == (0.0, 20.0, 300.0, 180.0)
|
||||
assert not points.points
|
||||
|
||||
|
||||
def test_empty_payloads_are_valid_and_predictable():
|
||||
for response in ("", "{}", "[]", '{"frames":[]}'):
|
||||
detections, points, normalized_json = parse_spatial_response(
|
||||
response,
|
||||
width=640,
|
||||
height=480,
|
||||
coordinate_mode="pixel",
|
||||
frame_count=5,
|
||||
fps=25,
|
||||
source="empty-test",
|
||||
)
|
||||
assert detections.frames == ()
|
||||
assert detections.frame_count == 5
|
||||
assert detections.fps == 25
|
||||
assert points.points == ()
|
||||
assert points.frame_count == 5
|
||||
normalized = json.loads(normalized_json)
|
||||
assert normalized["detections"]["frames"] == []
|
||||
assert normalized["points"]["points"] == []
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("response", "message"),
|
||||
[
|
||||
('{"bbox":[4,4,2,5]}', "x2 >= x1"),
|
||||
('{"polygon":[[1,1],[2,2]]}', "at least three"),
|
||||
('{"quad":[[0,0],[1,0],[1,1]]}', "exactly 4"),
|
||||
('{"point":[1]}', "two coordinates"),
|
||||
('{"score":2,"point":[1,1]}', "between 0 and 1"),
|
||||
(
|
||||
'{"bbox":[0,0,1,1],"polygon":[[0,0],[1,0],[0,1]],'
|
||||
'"quad":[[0,0],[1,0],[1,1],[0,1]]}',
|
||||
"either polygon",
|
||||
),
|
||||
(
|
||||
'{"bbox":[0,0,1,1],"coordinate_mode":"normalized_0_1"}',
|
||||
"parser is set",
|
||||
),
|
||||
('{"label":"no geometry"}', "requires bbox"),
|
||||
],
|
||||
)
|
||||
def test_strict_validation(response, message):
|
||||
with pytest.raises((TypeError, ValueError), match=message):
|
||||
parse_spatial_response(
|
||||
response,
|
||||
width=10,
|
||||
height=10,
|
||||
coordinate_mode="pixel",
|
||||
)
|
||||
|
||||
|
||||
def test_dimensions_timing_and_alias_conflicts_are_rejected():
|
||||
cases = [
|
||||
('{"media":{"width":20}}', {"width": 10}, "does not match"),
|
||||
('{"media":{"fps":30}}', {"fps": 24}, "does not match"),
|
||||
(
|
||||
'{"label":"a","class":"b","point":[1,1]}',
|
||||
{},
|
||||
"Conflicting aliases",
|
||||
),
|
||||
(
|
||||
'{"frames":[{"frame_index":0},{"frame_index":0}]}',
|
||||
{},
|
||||
"Duplicate frame_index",
|
||||
),
|
||||
(
|
||||
'{"detections":[],"objects":[]}',
|
||||
{},
|
||||
"multiple detection collection",
|
||||
),
|
||||
]
|
||||
for response, overrides, message in cases:
|
||||
arguments = {
|
||||
"width": 10,
|
||||
"height": 10,
|
||||
"coordinate_mode": "pixel",
|
||||
**overrides,
|
||||
}
|
||||
with pytest.raises(ValueError, match=message):
|
||||
parse_spatial_response(response, **arguments)
|
||||
|
||||
|
||||
def test_node_methods_return_direct_canonical_payloads():
|
||||
prompt = VLMSpatialPromptBuilder().build(
|
||||
"Locate the subject.",
|
||||
"pixel",
|
||||
100,
|
||||
80,
|
||||
1,
|
||||
0,
|
||||
)[0]
|
||||
detections, points, normalized = VLMStructuredSpatialParser().parse(
|
||||
'{"bbox_xyxy":[1,2,30,40],"point":[5,6]}',
|
||||
"pixel",
|
||||
100,
|
||||
80,
|
||||
)
|
||||
|
||||
assert isinstance(prompt, str)
|
||||
assert isinstance(detections, DetectionSequence)
|
||||
assert isinstance(points, PointSequence)
|
||||
assert json.loads(normalized)["version"] == 1
|
||||
@@ -0,0 +1,234 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import torch
|
||||
from ComfyUI_VLM_nodes.nodes.tracking import (
|
||||
VLMByteTracker,
|
||||
associate_detection_sequence,
|
||||
)
|
||||
from ComfyUI_VLM_nodes.nodes.vision_types import (
|
||||
Detection,
|
||||
DetectionSequence,
|
||||
FrameDetections,
|
||||
)
|
||||
|
||||
|
||||
def _frame(
|
||||
frame_index,
|
||||
detections,
|
||||
*,
|
||||
width=100,
|
||||
height=100,
|
||||
fps=10.0,
|
||||
):
|
||||
timestamp = frame_index / fps
|
||||
records = tuple(
|
||||
Detection(
|
||||
bbox_xyxy=record["box"],
|
||||
label=record.get("label"),
|
||||
score=record.get("score"),
|
||||
frame_index=frame_index,
|
||||
timestamp=timestamp,
|
||||
mask=record.get("mask"),
|
||||
)
|
||||
for record in detections
|
||||
)
|
||||
return FrameDetections(
|
||||
frame_index=frame_index,
|
||||
timestamp=timestamp,
|
||||
width=width,
|
||||
height=height,
|
||||
detections=records,
|
||||
)
|
||||
|
||||
|
||||
def _sequence(frames, *, frame_count=None, fps=10.0, width=100, height=100):
|
||||
return DetectionSequence(
|
||||
width=width,
|
||||
height=height,
|
||||
frames=tuple(frames),
|
||||
frame_count=frame_count or 0,
|
||||
fps=fps,
|
||||
source="test-detector",
|
||||
)
|
||||
|
||||
|
||||
def test_low_confidence_second_stage_keeps_the_track_id():
|
||||
sequence = _sequence(
|
||||
(
|
||||
_frame(
|
||||
0,
|
||||
[{"box": (10, 10, 30, 30), "score": 0.9, "label": "cat"}],
|
||||
),
|
||||
_frame(
|
||||
1,
|
||||
[{"box": (11, 10, 31, 30), "score": 0.25, "label": "cat"}],
|
||||
),
|
||||
)
|
||||
)
|
||||
tracks = associate_detection_sequence(
|
||||
sequence,
|
||||
high_threshold=0.6,
|
||||
low_threshold=0.1,
|
||||
min_hits=1,
|
||||
)
|
||||
assert len(tracks.tracks) == 1
|
||||
track = tracks.tracks[0]
|
||||
assert track.track_id == 0
|
||||
assert [item.track_id for item in track.detections] == [0, 0]
|
||||
assert track.detections[1].metadata["association_stage"] == "low"
|
||||
assert track.metadata["state"] == "active"
|
||||
|
||||
|
||||
def test_low_confidence_detection_cannot_start_a_track():
|
||||
sequence = _sequence(
|
||||
(
|
||||
_frame(
|
||||
0,
|
||||
[{"box": (10, 10, 30, 30), "score": 0.2, "label": "cat"}],
|
||||
),
|
||||
)
|
||||
)
|
||||
tracks = associate_detection_sequence(
|
||||
sequence,
|
||||
high_threshold=0.6,
|
||||
low_threshold=0.1,
|
||||
min_hits=1,
|
||||
)
|
||||
assert tracks.tracks == ()
|
||||
|
||||
|
||||
def test_label_aware_matching_prevents_cross_class_identity_reuse():
|
||||
frames = (
|
||||
_frame(
|
||||
0,
|
||||
[{"box": (10, 10, 30, 30), "score": 0.9, "label": "cat"}],
|
||||
),
|
||||
_frame(
|
||||
1,
|
||||
[{"box": (10, 10, 30, 30), "score": 0.9, "label": "dog"}],
|
||||
),
|
||||
)
|
||||
label_aware = associate_detection_sequence(
|
||||
_sequence(frames),
|
||||
min_hits=1,
|
||||
label_aware=True,
|
||||
emit_predictions=False,
|
||||
)
|
||||
class_agnostic = associate_detection_sequence(
|
||||
_sequence(frames),
|
||||
min_hits=1,
|
||||
label_aware=False,
|
||||
emit_predictions=False,
|
||||
)
|
||||
assert len(label_aware.tracks) == 2
|
||||
assert [track.label for track in label_aware.tracks] == ["cat", "dog"]
|
||||
assert len(class_agnostic.tracks) == 1
|
||||
assert [
|
||||
detection.frame_index for detection in class_agnostic.tracks[0].detections
|
||||
] == [0, 1]
|
||||
|
||||
|
||||
def test_max_age_seconds_uses_fps_and_marks_removed_deterministically():
|
||||
sequence = _sequence(
|
||||
(
|
||||
_frame(
|
||||
0,
|
||||
[{"box": (10, 10, 30, 30), "score": 0.9}],
|
||||
fps=2.0,
|
||||
),
|
||||
),
|
||||
frame_count=4,
|
||||
fps=2.0,
|
||||
)
|
||||
tracks = associate_detection_sequence(
|
||||
sequence,
|
||||
min_hits=1,
|
||||
max_age_seconds=1.0,
|
||||
emit_predictions=True,
|
||||
)
|
||||
track = tracks.tracks[0]
|
||||
assert [item.frame_index for item in track.detections] == [0, 1, 2]
|
||||
assert [item.metadata["observation"] for item in track.detections] == [
|
||||
"detected",
|
||||
"predicted",
|
||||
"predicted",
|
||||
]
|
||||
assert track.metadata["state"] == "removed"
|
||||
assert track.metadata["removed_frame"] == 3
|
||||
assert track.metadata["last_observed_frame"] == 0
|
||||
|
||||
|
||||
def test_mask_iou_can_rescue_a_zero_bbox_iou_match():
|
||||
mask = torch.zeros(100, 100)
|
||||
mask[40:60, 40:60] = 1
|
||||
sequence = _sequence(
|
||||
(
|
||||
_frame(
|
||||
0,
|
||||
[
|
||||
{
|
||||
"box": (0, 0, 10, 10),
|
||||
"score": 0.9,
|
||||
"mask": mask,
|
||||
}
|
||||
],
|
||||
),
|
||||
_frame(
|
||||
1,
|
||||
[
|
||||
{
|
||||
"box": (20, 0, 30, 10),
|
||||
"score": 0.9,
|
||||
"mask": mask,
|
||||
}
|
||||
],
|
||||
),
|
||||
)
|
||||
)
|
||||
tracks = VLMByteTracker(
|
||||
min_hits=1,
|
||||
motion_gate=1.0e12,
|
||||
).track(sequence)
|
||||
assert len(tracks.tracks) == 1
|
||||
assert len(tracks.tracks[0].detections) == 2
|
||||
|
||||
|
||||
def test_hungarian_results_and_serialization_are_repeatable():
|
||||
sequence = _sequence(
|
||||
(
|
||||
_frame(
|
||||
0,
|
||||
[
|
||||
{"box": (5, 5, 20, 20), "score": 0.9},
|
||||
{"box": (40, 5, 55, 20), "score": 0.9},
|
||||
],
|
||||
),
|
||||
_frame(
|
||||
1,
|
||||
[
|
||||
{"box": (41, 5, 56, 20), "score": 0.9},
|
||||
{"box": (6, 5, 21, 20), "score": 0.9},
|
||||
],
|
||||
),
|
||||
)
|
||||
)
|
||||
options = {"min_hits": 1, "emit_predictions": False}
|
||||
first = associate_detection_sequence(sequence, **options)
|
||||
second = associate_detection_sequence(sequence, **options)
|
||||
assert first.to_json() == second.to_json()
|
||||
assert [
|
||||
[detection.bbox_xyxy for detection in track.detections]
|
||||
for track in first.tracks
|
||||
] == [
|
||||
[(5.0, 5.0, 20.0, 20.0), (6.0, 5.0, 21.0, 20.0)],
|
||||
[(40.0, 5.0, 55.0, 20.0), (41.0, 5.0, 56.0, 20.0)],
|
||||
]
|
||||
|
||||
|
||||
def test_tracker_rejects_invalid_threshold_order():
|
||||
try:
|
||||
VLMByteTracker(high_threshold=0.2, low_threshold=0.3)
|
||||
except ValueError as error:
|
||||
assert "low_threshold" in str(error)
|
||||
else:
|
||||
raise AssertionError("Expected invalid threshold order to fail.")
|
||||
@@ -0,0 +1,378 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
from pathlib import Path
|
||||
|
||||
import pytest
|
||||
import torch
|
||||
|
||||
from ComfyUI_VLM_nodes.nodes.video_intelligence import (
|
||||
NODE_CLASS_MAPPINGS,
|
||||
VLMAdaptiveFrameSampler,
|
||||
build_scene_state,
|
||||
build_video_reasoning_prompt,
|
||||
parse_video_reasoning_output,
|
||||
resize_video_for_analysis,
|
||||
sample_video_frames,
|
||||
scene_state_summary,
|
||||
track_aware_crops,
|
||||
)
|
||||
from ComfyUI_VLM_nodes.nodes.vision_types import (
|
||||
Detection,
|
||||
EventSequence,
|
||||
SceneState,
|
||||
SelectedVideoFrame,
|
||||
Track,
|
||||
TrackSequence,
|
||||
VideoFrameSelection,
|
||||
)
|
||||
|
||||
|
||||
def _moving_video(frame_count=20, height=48, width=64):
|
||||
frames = torch.zeros((frame_count, height, width, 3), dtype=torch.float32)
|
||||
for frame_index in range(frame_count):
|
||||
x = min(width - 9, 2 + frame_index * 2)
|
||||
frames[frame_index, 16:28, x : x + 8, 0] = 1.0
|
||||
if frame_index >= frame_count // 2:
|
||||
frames[frame_index, :, :, 2] += 0.55
|
||||
return frames.clamp(0, 1)
|
||||
|
||||
|
||||
def _tracks(width=64, height=48, frame_count=20, fps=10.0):
|
||||
detections = []
|
||||
for frame_index in (0, 5, 10, 15, 19):
|
||||
x = min(width - 12, 2 + frame_index * 2)
|
||||
detections.append(
|
||||
Detection(
|
||||
bbox_xyxy=(x, 14, x + 10, 30),
|
||||
label="red object",
|
||||
score=0.9 - frame_index * 0.005,
|
||||
frame_index=frame_index,
|
||||
timestamp=frame_index / fps,
|
||||
track_id=3,
|
||||
metadata={"track_state": "active"},
|
||||
)
|
||||
)
|
||||
return TrackSequence(
|
||||
width=width,
|
||||
height=height,
|
||||
frame_count=frame_count,
|
||||
fps=fps,
|
||||
tracks=(
|
||||
Track(
|
||||
track_id=3,
|
||||
detections=tuple(detections),
|
||||
label="red object",
|
||||
score=0.85,
|
||||
),
|
||||
),
|
||||
source="unit-test-tracker",
|
||||
)
|
||||
|
||||
|
||||
def _selection():
|
||||
return VideoFrameSelection(
|
||||
width=64,
|
||||
height=48,
|
||||
source_frame_count=20,
|
||||
fps=10.0,
|
||||
strategy="Hybrid: scene + motion + tracks",
|
||||
frames=(
|
||||
SelectedVideoFrame(0, 0.0, 1.0, ("first-frame",)),
|
||||
SelectedVideoFrame(5, 0.5, 0.7, ("motion",)),
|
||||
SelectedVideoFrame(10, 1.0, 0.9, ("scene-change",)),
|
||||
SelectedVideoFrame(19, 1.9, 1.0, ("last-frame",)),
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
def test_uniform_sampling_is_deterministic_and_preserves_timestamps():
|
||||
frames = _moving_video()
|
||||
sampled, selection, diagnostics = sample_video_frames(
|
||||
frames,
|
||||
fps=10.0,
|
||||
max_frames=5,
|
||||
strategy="Uniform coverage",
|
||||
)
|
||||
assert sampled.shape == (5, 48, 64, 3)
|
||||
assert selection.indices == (0, 5, 10, 14, 19)
|
||||
assert selection.timestamps == pytest.approx((0.0, 0.5, 1.0, 1.4, 1.9))
|
||||
assert diagnostics["visual_reduction_ratio"] == pytest.approx(0.75)
|
||||
assert torch.equal(sampled[2], frames[10])
|
||||
|
||||
|
||||
def test_hybrid_sampling_captures_boundaries_scene_change_and_motion():
|
||||
frames = _moving_video()
|
||||
sampled, selection, diagnostics = sample_video_frames(
|
||||
frames,
|
||||
fps=10.0,
|
||||
max_frames=7,
|
||||
strategy="Hybrid: scene + motion + tracks",
|
||||
minimum_gap_seconds=0.2,
|
||||
)
|
||||
assert sampled.shape[0] == 7
|
||||
assert selection.indices[0] == 0
|
||||
assert selection.indices[-1] == 19
|
||||
assert any(9 <= index <= 11 for index in selection.indices)
|
||||
assert diagnostics["motion_peak"] > 0
|
||||
assert diagnostics["scene_peak"] > 0
|
||||
assert selection.to_json() == VideoFrameSelection.from_json(
|
||||
selection.to_json()
|
||||
).to_json()
|
||||
|
||||
|
||||
def test_track_priority_uses_track_changes_and_validates_dimensions():
|
||||
frames = _moving_video()
|
||||
tracks = _tracks()
|
||||
_sampled, selection, diagnostics = sample_video_frames(
|
||||
frames,
|
||||
fps=10.0,
|
||||
max_frames=6,
|
||||
strategy="Track-change priority",
|
||||
tracks=tracks,
|
||||
)
|
||||
assert diagnostics["track_peak"] == pytest.approx(1.0)
|
||||
assert any(
|
||||
"track-change" in frame.reasons for frame in selection.frames
|
||||
)
|
||||
bad_tracks = TrackSequence(
|
||||
width=65,
|
||||
height=48,
|
||||
frame_count=20,
|
||||
fps=10,
|
||||
tracks=(),
|
||||
)
|
||||
with pytest.raises(ValueError, match="dimensions"):
|
||||
sample_video_frames(
|
||||
frames,
|
||||
fps=10,
|
||||
max_frames=4,
|
||||
tracks=bad_tracks,
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"frames",
|
||||
[
|
||||
torch.zeros(4, 16, 16),
|
||||
torch.zeros(4, 16, 16, 2),
|
||||
torch.zeros(0, 16, 16, 3),
|
||||
torch.zeros(4, 16, 16, 3, dtype=torch.uint8),
|
||||
],
|
||||
)
|
||||
def test_sampling_rejects_invalid_video_tensors(frames):
|
||||
with pytest.raises((TypeError, ValueError)):
|
||||
sample_video_frames(frames, fps=24, max_frames=4)
|
||||
|
||||
|
||||
def test_track_aware_crops_preserve_identity_and_source_frame_mapping():
|
||||
frames = _moving_video()
|
||||
crops, manifest = track_aware_crops(
|
||||
frames,
|
||||
_tracks(),
|
||||
crops_per_track=3,
|
||||
max_crops=8,
|
||||
output_size=96,
|
||||
context_scale=1.4,
|
||||
)
|
||||
assert crops.shape == (3, 96, 96, 3)
|
||||
assert [item["track_id"] for item in manifest] == [3, 3, 3]
|
||||
assert [item["source_frame_index"] for item in manifest] == [0, 10, 19]
|
||||
assert crops.max().item() > 0.5
|
||||
|
||||
|
||||
def test_analysis_resize_reduces_pixels_without_changing_batch_or_aspect():
|
||||
frames = _moving_video(height=128, width=256)
|
||||
resized = resize_video_for_analysis(frames, max_side=128)
|
||||
assert resized.shape == (20, 64, 128, 3)
|
||||
assert resized.min().item() >= 0
|
||||
assert resized.max().item() <= 1
|
||||
assert resize_video_for_analysis(frames, max_side=0) is frames
|
||||
|
||||
|
||||
def test_scene_state_ignores_predicted_track_samples_and_computes_velocity():
|
||||
tracks = _tracks()
|
||||
predicted = Detection(
|
||||
bbox_xyxy=(48, 14, 58, 30),
|
||||
label="red object",
|
||||
frame_index=18,
|
||||
timestamp=1.8,
|
||||
track_id=3,
|
||||
metadata={"track_state": "predicted"},
|
||||
)
|
||||
track = tracks.tracks[0]
|
||||
with_prediction = TrackSequence(
|
||||
width=tracks.width,
|
||||
height=tracks.height,
|
||||
frame_count=tracks.frame_count,
|
||||
fps=tracks.fps,
|
||||
tracks=(
|
||||
Track(
|
||||
track_id=3,
|
||||
detections=tuple(
|
||||
sorted(
|
||||
(*track.detections, predicted),
|
||||
key=lambda item: item.frame_index,
|
||||
)
|
||||
),
|
||||
label=track.label,
|
||||
),
|
||||
),
|
||||
)
|
||||
scene = build_scene_state(with_prediction)
|
||||
assert len(scene.objects) == 1
|
||||
item = scene.objects[0]
|
||||
assert item.observation_count == 5
|
||||
assert item.velocity_xy_px_s[0] > 0
|
||||
assert "#3 red object" in scene_state_summary(scene)
|
||||
assert SceneState.from_json(scene.to_json()).to_json() == scene.to_json()
|
||||
|
||||
|
||||
def test_reasoning_prompt_explains_irregular_source_timeline():
|
||||
prompt = build_video_reasoning_prompt(
|
||||
_selection(),
|
||||
task="Robotics scene understanding",
|
||||
question="",
|
||||
max_events=12,
|
||||
)
|
||||
assert "irregularly spaced" in prompt
|
||||
assert "supplied image 2: source frame 10, timestamp 1.000000s" in prompt
|
||||
assert "Do not propose motor commands" in prompt
|
||||
assert "evidence_frame_indices" in prompt
|
||||
|
||||
|
||||
def test_structured_video_output_parses_fenced_json_and_preserves_evidence():
|
||||
response = """Result:
|
||||
```json
|
||||
{
|
||||
"summary": "A red object moves to the right.",
|
||||
"events": [
|
||||
{
|
||||
"start_time": 0.0,
|
||||
"end_time": 1.9,
|
||||
"label": "object motion",
|
||||
"text": "The red object moves from left to right.",
|
||||
"score": 0.94,
|
||||
"evidence_frame_indices": [0, 10, 19]
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
"""
|
||||
summary, events, normalized = parse_video_reasoning_output(
|
||||
response,
|
||||
_selection(),
|
||||
)
|
||||
assert summary == "A red object moves to the right."
|
||||
assert len(events.events) == 1
|
||||
assert events.events[0].metadata["evidence_frame_indices"] == (0, 10, 19)
|
||||
assert json.loads(normalized)["events"][0]["label"] == "object motion"
|
||||
|
||||
|
||||
def test_structured_output_normalizes_supplied_image_positions_to_source_frames():
|
||||
response = json.dumps(
|
||||
{
|
||||
"summary": "A transition occurs.",
|
||||
"events": [
|
||||
{
|
||||
"start_time": 0.5,
|
||||
"end_time": 1.9,
|
||||
"label": "transition",
|
||||
"text": "The scene changes.",
|
||||
"score": 0.8,
|
||||
# Positions 1 and 3 in the supplied image batch.
|
||||
"evidence_frame_indices": [1, 3],
|
||||
}
|
||||
],
|
||||
}
|
||||
)
|
||||
_summary, events, _normalized = parse_video_reasoning_output(
|
||||
response,
|
||||
_selection(),
|
||||
)
|
||||
event = events.events[0]
|
||||
assert event.metadata["evidence_frame_indices"] == (5, 19)
|
||||
assert event.metadata["evidence_index_mode"] == "supplied-image-position"
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("event_patch", "error"),
|
||||
[
|
||||
({"end_time": 2.1}, "outside"),
|
||||
({"score": 1.2}, "between"),
|
||||
({"evidence_frame_indices": [0, 7]}, "not supplied"),
|
||||
({"evidence_frame_indices": [0, 0]}, "duplicate"),
|
||||
({"label": "", "text": ""}, "requires"),
|
||||
],
|
||||
)
|
||||
def test_structured_video_output_rejects_unverifiable_events(event_patch, error):
|
||||
event = {
|
||||
"start_time": 0.0,
|
||||
"end_time": 1.0,
|
||||
"label": "motion",
|
||||
"text": "Object moves.",
|
||||
"score": 0.8,
|
||||
"evidence_frame_indices": [0, 10],
|
||||
}
|
||||
event.update(event_patch)
|
||||
with pytest.raises((TypeError, ValueError), match=error):
|
||||
parse_video_reasoning_output(
|
||||
json.dumps({"summary": "test", "events": [event]}),
|
||||
_selection(),
|
||||
)
|
||||
|
||||
|
||||
def test_scene_state_accepts_validated_events():
|
||||
_summary, events, _normalized = parse_video_reasoning_output(
|
||||
json.dumps(
|
||||
{
|
||||
"summary": "motion",
|
||||
"events": [
|
||||
{
|
||||
"start_time": 0.0,
|
||||
"end_time": 1.9,
|
||||
"label": "motion",
|
||||
"text": "Object moves.",
|
||||
"score": 0.9,
|
||||
"evidence_frame_indices": [0, 19],
|
||||
}
|
||||
],
|
||||
}
|
||||
),
|
||||
_selection(),
|
||||
)
|
||||
scene = build_scene_state(_tracks(), events)
|
||||
assert isinstance(events, EventSequence)
|
||||
assert len(scene.events) == 1
|
||||
assert "Event 0.000s–1.900s" in scene_state_summary(scene)
|
||||
|
||||
|
||||
def test_node_surface_registers_all_video_intelligence_nodes():
|
||||
assert set(NODE_CLASS_MAPPINGS) == {
|
||||
"VLMAdaptiveFrameSampler",
|
||||
"VLMTrackAwareCrops",
|
||||
"VLMBuildSceneState",
|
||||
"VLMVideoReasoningPrompt",
|
||||
"VLMEventsFromVideoJSON",
|
||||
"VLMVideoTemporalReasoner",
|
||||
}
|
||||
inputs = VLMAdaptiveFrameSampler.INPUT_TYPES()
|
||||
assert inputs["required"]["frames"][0] == "IMAGE"
|
||||
assert inputs["optional"]["tracks"][0] == "VLM_TRACKS"
|
||||
reasoner = NODE_CLASS_MAPPINGS["VLMVideoTemporalReasoner"]
|
||||
assert reasoner.RETURN_NAMES[-2:] == ("events_json", "selection_json")
|
||||
|
||||
|
||||
def test_api_example_uses_direct_json_outputs_and_preview():
|
||||
example = json.loads(
|
||||
(
|
||||
Path(__file__).resolve().parents[1]
|
||||
/ "examples"
|
||||
/ "vision"
|
||||
/ "video_temporal_reasoning_api.json"
|
||||
).read_text(encoding="utf-8")
|
||||
)
|
||||
assert example["3"]["class_type"] == "VLMVideoTemporalReasoner"
|
||||
assert example["5"]["inputs"]["text"] == ["3", 6]
|
||||
assert example["6"]["inputs"]["text"] == ["3", 7]
|
||||
assert example["8"]["inputs"]["images"] == ["3", 3]
|
||||
@@ -0,0 +1,273 @@
|
||||
import importlib
|
||||
import json
|
||||
from dataclasses import FrozenInstanceError
|
||||
from pathlib import Path
|
||||
|
||||
import pytest
|
||||
import torch
|
||||
|
||||
PACKAGE = Path(__file__).resolve().parents[1].name
|
||||
vision_types = importlib.import_module(f"{PACKAGE}.nodes.vision_types")
|
||||
|
||||
DETECTIONS_SCHEMA = vision_types.DETECTIONS_SCHEMA
|
||||
EVENTS_SCHEMA = vision_types.EVENTS_SCHEMA
|
||||
POINTS_SCHEMA = vision_types.POINTS_SCHEMA
|
||||
SCHEMA_VERSION = vision_types.SCHEMA_VERSION
|
||||
SCENE_STATE_SCHEMA = vision_types.SCENE_STATE_SCHEMA
|
||||
TRACKS_SCHEMA = vision_types.TRACKS_SCHEMA
|
||||
VIDEO_SELECTION_SCHEMA = vision_types.VIDEO_SELECTION_SCHEMA
|
||||
VLM_DETECTIONS = vision_types.VLM_DETECTIONS
|
||||
VLM_EVENTS = vision_types.VLM_EVENTS
|
||||
VLM_POINTS = vision_types.VLM_POINTS
|
||||
VLM_SCENE_STATE = vision_types.VLM_SCENE_STATE
|
||||
VLM_TRACKS = vision_types.VLM_TRACKS
|
||||
VLM_VIDEO_SELECTION = vision_types.VLM_VIDEO_SELECTION
|
||||
Detection = vision_types.Detection
|
||||
DetectionSequence = vision_types.DetectionSequence
|
||||
EventSequence = vision_types.EventSequence
|
||||
FrameDetections = vision_types.FrameDetections
|
||||
FrozenDict = vision_types.FrozenDict
|
||||
PointSequence = vision_types.PointSequence
|
||||
TemporalEvent = vision_types.TemporalEvent
|
||||
Track = vision_types.Track
|
||||
TrackSequence = vision_types.TrackSequence
|
||||
VisionPoint = vision_types.VisionPoint
|
||||
|
||||
|
||||
def sample_sequence() -> DetectionSequence:
|
||||
mask = torch.zeros((24, 32), dtype=torch.float32)
|
||||
mask[3:12, 4:18] = 1
|
||||
first = Detection(
|
||||
bbox_xyxy=(4, 3, 18, 12),
|
||||
label="cat",
|
||||
text="sleeping cat",
|
||||
score=0.875,
|
||||
polygon=((4, 3), (18, 3), (18, 12), (4, 12)),
|
||||
quad=((4, 3), (18, 3), (18, 12), (4, 12)),
|
||||
frame_index=0,
|
||||
timestamp=0.0,
|
||||
track_id=7,
|
||||
source="unit-test",
|
||||
metadata={"attributes": ["small", "red"], "visible": True},
|
||||
mask=mask,
|
||||
)
|
||||
second = Detection(
|
||||
bbox_xyxy=(6.5, 5.0, 20.25, 15.0),
|
||||
label="cat",
|
||||
score=0.8,
|
||||
frame_index=1,
|
||||
timestamp=0.5,
|
||||
track_id=7,
|
||||
)
|
||||
return DetectionSequence(
|
||||
width=32,
|
||||
height=24,
|
||||
frame_count=2,
|
||||
fps=2.0,
|
||||
source="synthetic",
|
||||
metadata={"nested": {"value": 3}},
|
||||
frames=(
|
||||
FrameDetections(
|
||||
frame_index=0,
|
||||
timestamp=0.0,
|
||||
width=32,
|
||||
height=24,
|
||||
detections=(first,),
|
||||
),
|
||||
FrameDetections(
|
||||
frame_index=1,
|
||||
timestamp=0.5,
|
||||
width=32,
|
||||
height=24,
|
||||
detections=(second,),
|
||||
),
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
def test_public_socket_and_schema_names_are_stable():
|
||||
assert VLM_DETECTIONS == "VLM_DETECTIONS"
|
||||
assert VLM_TRACKS == "VLM_TRACKS"
|
||||
assert VLM_POINTS == "VLM_POINTS"
|
||||
assert VLM_EVENTS == "VLM_EVENTS"
|
||||
assert VLM_VIDEO_SELECTION == "VLM_VIDEO_SELECTION"
|
||||
assert VLM_SCENE_STATE == "VLM_SCENE_STATE"
|
||||
assert SCHEMA_VERSION == 1
|
||||
assert DETECTIONS_SCHEMA == "comfyui-vlm/detections"
|
||||
assert TRACKS_SCHEMA == "comfyui-vlm/tracks"
|
||||
assert POINTS_SCHEMA == "comfyui-vlm/points"
|
||||
assert EVENTS_SCHEMA == "comfyui-vlm/events"
|
||||
assert VIDEO_SELECTION_SCHEMA == "comfyui-vlm/video-selection"
|
||||
assert SCENE_STATE_SCHEMA == "comfyui-vlm/scene-state"
|
||||
|
||||
|
||||
def test_detection_payload_is_validated_immutable_and_mask_safe():
|
||||
original = torch.ones((4, 5))
|
||||
detection = Detection(
|
||||
bbox_xyxy=(0, 0, 5, 4),
|
||||
label="object",
|
||||
score=1.0,
|
||||
metadata={"items": [1, {"ready": True}]},
|
||||
mask=original,
|
||||
)
|
||||
original.zero_()
|
||||
assert detection.mask.sum().item() == 20
|
||||
assert isinstance(detection.metadata, FrozenDict)
|
||||
assert detection.metadata["items"][1]["ready"] is True
|
||||
|
||||
with pytest.raises(FrozenInstanceError):
|
||||
detection.label = "changed"
|
||||
with pytest.raises(TypeError):
|
||||
detection.metadata["new"] = "value"
|
||||
with pytest.raises(TypeError, match="Metadata"):
|
||||
Detection(
|
||||
bbox_xyxy=(0, 0, 1, 1),
|
||||
metadata={"tensor": torch.ones(1)},
|
||||
)
|
||||
|
||||
record = detection.to_dict()
|
||||
assert "mask" not in record
|
||||
assert "mask" not in json.dumps(record)
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
("kwargs", "error"),
|
||||
[
|
||||
({"bbox_xyxy": (2, 0, 1, 2)}, "x2"),
|
||||
({"bbox_xyxy": (-1, 0, 1, 2)}, "non-negative"),
|
||||
({"bbox_xyxy": (0, 0, 1, 2), "score": 1.1}, "between 0 and 1"),
|
||||
({"bbox_xyxy": (0, 0, 1, 2), "frame_index": -1}, "frame_index"),
|
||||
({"bbox_xyxy": (0, 0, 1, 2), "timestamp": -0.1}, "timestamp"),
|
||||
(
|
||||
{"bbox_xyxy": (0, 0, 1, 2), "quad": ((0, 0), (1, 0), (1, 1))},
|
||||
"exactly 4",
|
||||
),
|
||||
(
|
||||
{"bbox_xyxy": (0, 0, 1, 2), "mask": torch.ones(1, 2, 3)},
|
||||
"shape",
|
||||
),
|
||||
],
|
||||
)
|
||||
def test_detection_rejects_invalid_values(kwargs, error):
|
||||
with pytest.raises((TypeError, ValueError), match=error):
|
||||
Detection(**kwargs)
|
||||
|
||||
|
||||
def test_detection_sequence_json_round_trip_is_versioned_and_tensor_free():
|
||||
sequence = sample_sequence()
|
||||
encoded = sequence.to_json(indent=2)
|
||||
decoded_json = json.loads(encoded)
|
||||
assert decoded_json["schema"] == DETECTIONS_SCHEMA
|
||||
assert decoded_json["version"] == SCHEMA_VERSION
|
||||
assert decoded_json["media"] == {
|
||||
"fps": 2.0,
|
||||
"frame_count": 2,
|
||||
"height": 24,
|
||||
"width": 32,
|
||||
}
|
||||
assert "mask" not in encoded
|
||||
|
||||
restored = DetectionSequence.from_json(encoded)
|
||||
assert restored.to_dict() == sequence.to_dict()
|
||||
assert restored.frames[0].detections[0].mask is None
|
||||
assert restored.all_detections()[1].center == pytest.approx((13.375, 10.0))
|
||||
assert restored.frame(99) is None
|
||||
|
||||
decoded_json["version"] = 99
|
||||
with pytest.raises(ValueError, match="Unsupported"):
|
||||
DetectionSequence.from_dict(decoded_json)
|
||||
decoded_json["version"] = SCHEMA_VERSION
|
||||
decoded_json["schema"] = "other"
|
||||
with pytest.raises(ValueError, match="Expected schema"):
|
||||
DetectionSequence.from_dict(decoded_json)
|
||||
|
||||
|
||||
def test_frame_and_sequence_enforce_dimensions_order_and_timestamps():
|
||||
detection = Detection(
|
||||
bbox_xyxy=(0, 0, 11, 5),
|
||||
frame_index=0,
|
||||
timestamp=0,
|
||||
)
|
||||
with pytest.raises(ValueError, match="width"):
|
||||
FrameDetections(
|
||||
frame_index=0,
|
||||
timestamp=0,
|
||||
width=10,
|
||||
height=10,
|
||||
detections=(detection,),
|
||||
)
|
||||
mismatch = Detection(
|
||||
bbox_xyxy=(0, 0, 1, 1),
|
||||
frame_index=1,
|
||||
timestamp=0,
|
||||
)
|
||||
with pytest.raises(ValueError, match="frame_index"):
|
||||
FrameDetections(
|
||||
frame_index=0,
|
||||
timestamp=0,
|
||||
width=10,
|
||||
height=10,
|
||||
detections=(mismatch,),
|
||||
)
|
||||
|
||||
frame_one = FrameDetections(1, 1.0, 10, 10)
|
||||
frame_zero = FrameDetections(0, 0.0, 10, 10)
|
||||
with pytest.raises(ValueError, match="increasing"):
|
||||
DetectionSequence(10, 10, frames=(frame_one, frame_zero))
|
||||
|
||||
|
||||
def test_point_track_and_event_schemas_round_trip_without_tensors():
|
||||
sequence = sample_sequence()
|
||||
points = PointSequence(
|
||||
width=32,
|
||||
height=24,
|
||||
frame_count=2,
|
||||
fps=2,
|
||||
points=(
|
||||
VisionPoint(
|
||||
x=11,
|
||||
y=7.5,
|
||||
label="cat",
|
||||
score=0.8,
|
||||
frame_index=0,
|
||||
track_id=7,
|
||||
),
|
||||
),
|
||||
)
|
||||
assert PointSequence.from_json(points.to_json()).to_dict() == points.to_dict()
|
||||
|
||||
track = Track(
|
||||
track_id=7,
|
||||
label="cat",
|
||||
score=0.8,
|
||||
detections=sequence.all_detections(),
|
||||
)
|
||||
tracks = TrackSequence(
|
||||
width=32,
|
||||
height=24,
|
||||
frame_count=2,
|
||||
fps=2,
|
||||
tracks=(track,),
|
||||
)
|
||||
restored_tracks = TrackSequence.from_json(tracks.to_json())
|
||||
assert restored_tracks.to_dict() == tracks.to_dict()
|
||||
assert "mask" not in tracks.to_json()
|
||||
|
||||
events = EventSequence(
|
||||
duration=2.0,
|
||||
events=(
|
||||
TemporalEvent(
|
||||
start_time=0.25,
|
||||
end_time=1.5,
|
||||
label="movement",
|
||||
text="the cat moves",
|
||||
score=0.9,
|
||||
),
|
||||
),
|
||||
)
|
||||
assert EventSequence.from_json(events.to_json()).to_dict() == events.to_dict()
|
||||
with pytest.raises(ValueError, match="duration"):
|
||||
EventSequence(
|
||||
duration=1.0,
|
||||
events=(TemporalEvent(0.0, 2.0),),
|
||||
)
|
||||
@@ -0,0 +1,432 @@
|
||||
import importlib
|
||||
import inspect
|
||||
import json
|
||||
from pathlib import Path
|
||||
|
||||
import pytest
|
||||
import torch
|
||||
|
||||
PACKAGE = Path(__file__).resolve().parents[1].name
|
||||
vision_types = importlib.import_module(f"{PACKAGE}.nodes.vision_types")
|
||||
vision_utils = importlib.import_module(f"{PACKAGE}.nodes.vision_utils")
|
||||
|
||||
VLM_DETECTIONS = vision_types.VLM_DETECTIONS
|
||||
VLM_POINTS = vision_types.VLM_POINTS
|
||||
Detection = vision_types.Detection
|
||||
DetectionSequence = vision_types.DetectionSequence
|
||||
FrameDetections = vision_types.FrameDetections
|
||||
BOUNDING_BOXES = vision_utils.BOUNDING_BOXES
|
||||
NODE_CLASS_MAPPINGS = vision_utils.NODE_CLASS_MAPPINGS
|
||||
VLMCropDetections = vision_utils.VLMCropDetections
|
||||
VLMDetectionsFromJSON = vision_utils.VLMDetectionsFromJSON
|
||||
VLMDetectionsToBoundingBoxes = vision_utils.VLMDetectionsToBoundingBoxes
|
||||
VLMDetectionsToJSON = vision_utils.VLMDetectionsToJSON
|
||||
VLMDetectionsToMasks = vision_utils.VLMDetectionsToMasks
|
||||
VLMDetectionsToPoints = vision_utils.VLMDetectionsToPoints
|
||||
VLMFilterDetections = vision_utils.VLMFilterDetections
|
||||
VLMMaskComposite = vision_utils.VLMMaskComposite
|
||||
VLMMaskProcessor = vision_utils.VLMMaskProcessor
|
||||
VLMRenderDetections = vision_utils.VLMRenderDetections
|
||||
VLMSelectDetection = vision_utils.VLMSelectDetection
|
||||
bounding_boxes_payload = vision_utils.bounding_boxes_payload
|
||||
composite_with_mask = vision_utils.composite_with_mask
|
||||
crop_detections = vision_utils.crop_detections
|
||||
detection_centers = vision_utils.detection_centers
|
||||
filter_detection_sequence = vision_utils.filter_detection_sequence
|
||||
instance_map_images = vision_utils.instance_map_images
|
||||
masks_to_images = vision_utils.masks_to_images
|
||||
process_masks = vision_utils.process_masks
|
||||
render_detections = vision_utils.render_detections
|
||||
select_detection_sequence = vision_utils.select_detection_sequence
|
||||
sequence_masks = vision_utils.sequence_masks
|
||||
|
||||
|
||||
def sample_sequence() -> DetectionSequence:
|
||||
cat_mask = torch.zeros((16, 20))
|
||||
cat_mask[2:8, 3:10] = 1
|
||||
return DetectionSequence(
|
||||
width=20,
|
||||
height=16,
|
||||
frame_count=2,
|
||||
fps=2,
|
||||
frames=(
|
||||
FrameDetections(
|
||||
frame_index=0,
|
||||
timestamp=0,
|
||||
width=20,
|
||||
height=16,
|
||||
detections=(
|
||||
Detection(
|
||||
bbox_xyxy=(3.2, 2.1, 10.0, 8.0),
|
||||
label="cat",
|
||||
score=0.9,
|
||||
frame_index=0,
|
||||
timestamp=0,
|
||||
track_id=5,
|
||||
mask=cat_mask,
|
||||
),
|
||||
Detection(
|
||||
bbox_xyxy=(12, 4, 18, 13),
|
||||
label="dog",
|
||||
score=0.55,
|
||||
frame_index=0,
|
||||
timestamp=0,
|
||||
),
|
||||
),
|
||||
),
|
||||
FrameDetections(
|
||||
frame_index=1,
|
||||
timestamp=0.5,
|
||||
width=20,
|
||||
height=16,
|
||||
detections=(
|
||||
Detection(
|
||||
bbox_xyxy=(5, 3, 12, 10),
|
||||
label="cat",
|
||||
score=0.8,
|
||||
frame_index=1,
|
||||
timestamp=0.5,
|
||||
track_id=5,
|
||||
),
|
||||
),
|
||||
),
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
def empty_sequence() -> DetectionSequence:
|
||||
return DetectionSequence(
|
||||
width=20,
|
||||
height=16,
|
||||
frame_count=2,
|
||||
frames=(
|
||||
FrameDetections(0, 0, 20, 16),
|
||||
FrameDetections(1, 1, 20, 16),
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
def test_filter_and_select_by_all_supported_fields():
|
||||
sequence = sample_sequence()
|
||||
filtered = filter_detection_sequence(
|
||||
sequence,
|
||||
label="CAT",
|
||||
label_mode="exact",
|
||||
minimum_score=0.85,
|
||||
minimum_area=30,
|
||||
maximum_area=50,
|
||||
track_id=5,
|
||||
frame_index=0,
|
||||
)
|
||||
assert len(filtered.frames) == 1
|
||||
assert [item.label for item in filtered.all_detections()] == ["cat"]
|
||||
|
||||
contains = filter_detection_sequence(
|
||||
sequence,
|
||||
label="o",
|
||||
minimum_score=0.5,
|
||||
)
|
||||
assert [item.label for item in contains.all_detections()] == ["dog"]
|
||||
|
||||
selected = select_detection_sequence(sequence, 1)
|
||||
assert [item.label for item in selected.all_detections()] == ["dog"]
|
||||
missing = select_detection_sequence(sequence, 100)
|
||||
assert missing.all_detections() == ()
|
||||
assert len(missing.frames) == 2
|
||||
|
||||
with pytest.raises(ValueError, match="maximum_area"):
|
||||
filter_detection_sequence(
|
||||
sequence,
|
||||
minimum_area=10,
|
||||
maximum_area=5,
|
||||
)
|
||||
|
||||
|
||||
def test_core_bounding_boxes_are_integer_xywh_with_metadata():
|
||||
payload = bounding_boxes_payload(sample_sequence())
|
||||
assert payload[0] == {
|
||||
"x": 3,
|
||||
"y": 2,
|
||||
"width": 7,
|
||||
"height": 6,
|
||||
"metadata": {
|
||||
"bbox_xyxy": [3.2, 2.1, 10.0, 8.0],
|
||||
"frame_index": 0,
|
||||
"timestamp": 0.0,
|
||||
"label": "cat",
|
||||
"score": 0.9,
|
||||
"track_id": 5,
|
||||
},
|
||||
}
|
||||
assert payload[2]["x"] == 5
|
||||
assert payload[2]["metadata"]["frame_index"] == 1
|
||||
assert bounding_boxes_payload(empty_sequence()) == []
|
||||
|
||||
|
||||
def test_centers_and_masks_preserve_frame_mapping_and_empty_shapes():
|
||||
sequence = sample_sequence()
|
||||
points = detection_centers(sequence)
|
||||
assert points.points[0].x == pytest.approx(6.6)
|
||||
assert points.points[0].y == pytest.approx(5.05)
|
||||
assert points.points[0].track_id == 5
|
||||
assert json.loads(points.to_json())["schema"] == "comfyui-vlm/points"
|
||||
|
||||
unions, individuals, mapping = sequence_masks(sequence)
|
||||
assert unions.shape == (2, 16, 20)
|
||||
assert individuals.shape == (3, 16, 20)
|
||||
assert unions[0].sum() > 0
|
||||
assert mapping[0] == {
|
||||
"mask_index": 0,
|
||||
"frame_index": 0,
|
||||
"detection_index": 0,
|
||||
"label": "cat",
|
||||
"track_id": 5,
|
||||
}
|
||||
|
||||
empty_unions, empty_individuals, empty_mapping = sequence_masks(empty_sequence())
|
||||
assert empty_unions.shape == (2, 16, 20)
|
||||
assert empty_unions.sum() == 0
|
||||
assert empty_individuals.shape == (0, 16, 20)
|
||||
assert empty_mapping == []
|
||||
|
||||
|
||||
def test_creator_mask_outputs_are_binary_previewable_and_instance_colored():
|
||||
sequence = sample_sequence()
|
||||
unions, individuals, _mapping = sequence_masks(sequence)
|
||||
union_images = masks_to_images(unions)
|
||||
individual_images = masks_to_images(individuals)
|
||||
instance_maps = instance_map_images(sequence)
|
||||
|
||||
assert set(torch.unique(unions).tolist()) <= {0.0, 1.0}
|
||||
assert set(torch.unique(individuals).tolist()) <= {0.0, 1.0}
|
||||
assert union_images.shape == (2, 16, 20, 3)
|
||||
assert individual_images.shape == (3, 16, 20, 3)
|
||||
assert torch.equal(union_images[..., 0], unions)
|
||||
assert torch.equal(union_images[..., 0], union_images[..., 2])
|
||||
assert instance_maps.shape == (2, 16, 20, 3)
|
||||
assert instance_maps.sum() > 0
|
||||
assert torch.equal(instance_maps, instance_map_images(sequence))
|
||||
|
||||
|
||||
def test_mask_processing_grow_shrink_feather_and_inverse_are_batch_safe():
|
||||
mask = torch.zeros((2, 9, 9))
|
||||
mask[:, 4, 4] = 1
|
||||
grown, grown_binary, grown_inverse = process_masks(
|
||||
mask,
|
||||
threshold=0.5,
|
||||
grow_shrink=1,
|
||||
feather_radius=0,
|
||||
)
|
||||
assert grown.shape == mask.shape
|
||||
assert grown[0].sum() == 9
|
||||
assert torch.equal(grown, grown_binary)
|
||||
assert torch.allclose(grown + grown_inverse, torch.ones_like(grown))
|
||||
|
||||
soft, binary, inverse = process_masks(
|
||||
mask,
|
||||
threshold=0.5,
|
||||
grow_shrink=2,
|
||||
feather_radius=2,
|
||||
)
|
||||
assert binary[0].sum() == 25
|
||||
assert torch.any((soft > 0) & (soft < 1))
|
||||
assert torch.allclose(soft + inverse, torch.ones_like(soft), atol=1e-6)
|
||||
|
||||
full = torch.ones((1, 9, 9))
|
||||
shrunk, _, _ = process_masks(full, grow_shrink=-1)
|
||||
assert shrunk[0, 0].sum() == 0
|
||||
assert shrunk[0, -1].sum() == 0
|
||||
with pytest.raises(ValueError, match="threshold"):
|
||||
process_masks(mask, threshold=2)
|
||||
|
||||
|
||||
def test_mask_composite_splits_foreground_and_broadcasts_video_batches():
|
||||
image = torch.zeros((2, 4, 5, 3))
|
||||
image[..., 0] = 1
|
||||
mask = torch.zeros((1, 4, 5))
|
||||
mask[:, :, :2] = 1
|
||||
replacement = torch.zeros((1, 4, 5, 3))
|
||||
replacement[..., 2] = 1
|
||||
|
||||
composite, foreground, background_only, mask_image = composite_with_mask(
|
||||
image,
|
||||
mask,
|
||||
background=replacement,
|
||||
)
|
||||
assert composite.shape == image.shape
|
||||
assert foreground.shape == image.shape
|
||||
assert background_only.shape == image.shape
|
||||
assert mask_image.shape == image.shape
|
||||
assert torch.all(composite[:, :, :2, 0] == 1)
|
||||
assert torch.all(composite[:, :, 2:, 2] == 1)
|
||||
assert foreground[:, :, 2:].sum() == 0
|
||||
assert background_only[:, :, :2].sum() == 0
|
||||
|
||||
solid, *_ = composite_with_mask(
|
||||
image[:1],
|
||||
mask,
|
||||
background_color="#0f0",
|
||||
)
|
||||
assert torch.all(solid[:, :, 2:, 1] == 1)
|
||||
with pytest.raises(ValueError, match="dimensions"):
|
||||
composite_with_mask(image, torch.zeros((1, 3, 3)))
|
||||
|
||||
|
||||
def test_rendering_is_deterministic_batch_safe_and_empty_safe():
|
||||
image = torch.zeros((2, 16, 20, 3), dtype=torch.float32)
|
||||
sequence = sample_sequence()
|
||||
first = render_detections(
|
||||
image,
|
||||
sequence,
|
||||
draw_masks=True,
|
||||
draw_labels=True,
|
||||
)
|
||||
second = render_detections(
|
||||
image,
|
||||
sequence,
|
||||
draw_masks=True,
|
||||
draw_labels=True,
|
||||
)
|
||||
assert first.shape == image.shape
|
||||
assert torch.equal(first, second)
|
||||
assert first.sum() > 0
|
||||
|
||||
unchanged = render_detections(image, empty_sequence())
|
||||
assert torch.equal(unchanged, image)
|
||||
with pytest.raises(ValueError, match="dimensions"):
|
||||
render_detections(
|
||||
torch.zeros((2, 10, 10, 3)),
|
||||
sequence,
|
||||
)
|
||||
|
||||
|
||||
def test_padded_square_crops_form_a_non_distorted_image_batch():
|
||||
image = torch.zeros((2, 16, 20, 3), dtype=torch.float32)
|
||||
image[0, 2:8, 3:10, 0] = 1
|
||||
image[0, 4:13, 12:18, 1] = 1
|
||||
image[1, 3:10, 5:12, 2] = 1
|
||||
crops, metadata = crop_detections(
|
||||
image,
|
||||
sample_sequence(),
|
||||
padding=1,
|
||||
square=True,
|
||||
)
|
||||
assert crops.shape[0] == 3
|
||||
assert crops.ndim == 4
|
||||
assert crops.shape[1] == max(record["valid_height"] for record in metadata)
|
||||
assert crops.shape[2] == max(record["valid_width"] for record in metadata)
|
||||
assert all(record["batch_width"] == crops.shape[2] for record in metadata)
|
||||
assert metadata[0]["track_id"] == 5
|
||||
valid_crop = crops[
|
||||
0,
|
||||
: metadata[0]["valid_height"],
|
||||
: metadata[0]["valid_width"],
|
||||
]
|
||||
assert valid_crop.sum() > 0
|
||||
|
||||
empty_crops, empty_metadata = crop_detections(image, empty_sequence())
|
||||
assert empty_crops.shape == (0, 1, 1, 3)
|
||||
assert empty_metadata == []
|
||||
|
||||
|
||||
def test_utility_node_contracts_and_json_round_trip():
|
||||
sequence = sample_sequence()
|
||||
encoded = VLMDetectionsToJSON().serialize(sequence, pretty=False)[0]
|
||||
restored = VLMDetectionsFromJSON().parse(encoded)[0]
|
||||
assert restored.to_dict() == sequence.to_dict()
|
||||
|
||||
filtered = VLMFilterDetections().filter(
|
||||
sequence,
|
||||
label="cat",
|
||||
label_mode="exact",
|
||||
minimum_score=0,
|
||||
minimum_area=0,
|
||||
maximum_area=0,
|
||||
track_id=-1,
|
||||
frame_index=-1,
|
||||
)[0]
|
||||
assert len(filtered.all_detections()) == 2
|
||||
assert len(VLMSelectDetection().select(sequence, 0)[0].all_detections()) == 1
|
||||
|
||||
boxes, boxes_json = VLMDetectionsToBoundingBoxes().convert(sequence)
|
||||
assert json.loads(boxes_json) == boxes
|
||||
points, points_json = VLMDetectionsToPoints().convert(sequence)
|
||||
assert json.loads(points_json) == points.to_dict()
|
||||
(
|
||||
union,
|
||||
individual,
|
||||
mask_json,
|
||||
inverse,
|
||||
union_images,
|
||||
individual_images,
|
||||
instance_maps,
|
||||
) = VLMDetectionsToMasks().convert(sequence)
|
||||
assert union.shape[0] == 2
|
||||
assert individual.shape[0] == 3
|
||||
assert len(json.loads(mask_json)) == 3
|
||||
assert torch.allclose(union + inverse, torch.ones_like(union))
|
||||
assert union_images.shape == (2, 16, 20, 3)
|
||||
assert individual_images.shape == (3, 16, 20, 3)
|
||||
assert instance_maps.shape == (2, 16, 20, 3)
|
||||
|
||||
processed = VLMMaskProcessor().process(union, 0.5, 1, 1)
|
||||
assert [value.shape[0] for value in processed] == [2, 2, 2, 2]
|
||||
composited = VLMMaskComposite().composite(
|
||||
torch.ones((2, 16, 20, 3)),
|
||||
union,
|
||||
"#000000",
|
||||
)
|
||||
assert all(value.shape == (2, 16, 20, 3) for value in composited)
|
||||
|
||||
image = torch.zeros((2, 16, 20, 3))
|
||||
assert (
|
||||
VLMRenderDetections()
|
||||
.render(
|
||||
image,
|
||||
sequence,
|
||||
True,
|
||||
False,
|
||||
0.25,
|
||||
2,
|
||||
)[0]
|
||||
.shape
|
||||
== image.shape
|
||||
)
|
||||
crops, crop_json = VLMCropDetections().crop(image, sequence, 0, False)
|
||||
assert crops.shape[0] == 3
|
||||
assert len(json.loads(crop_json)) == 3
|
||||
|
||||
|
||||
def test_every_utility_node_accepts_its_declared_inputs():
|
||||
expected = {
|
||||
"VLMDetectionsFromJSON",
|
||||
"VLMDetectionsToJSON",
|
||||
"VLMFilterDetections",
|
||||
"VLMSelectDetection",
|
||||
"VLMDetectionsToBoundingBoxes",
|
||||
"VLMDetectionsToPoints",
|
||||
"VLMDetectionsToMasks",
|
||||
"VLMMaskProcessor",
|
||||
"VLMMaskComposite",
|
||||
"VLMRenderDetections",
|
||||
"VLMCropDetections",
|
||||
}
|
||||
assert set(NODE_CLASS_MAPPINGS) == expected
|
||||
assert VLMDetectionsFromJSON.RETURN_TYPES == (VLM_DETECTIONS,)
|
||||
assert VLMDetectionsToBoundingBoxes.RETURN_TYPES[0] == BOUNDING_BOXES
|
||||
assert VLMDetectionsToPoints.RETURN_TYPES[0] == VLM_POINTS
|
||||
|
||||
for node_class in NODE_CLASS_MAPPINGS.values():
|
||||
schema = node_class.INPUT_TYPES()
|
||||
declared = {
|
||||
name
|
||||
for group in schema.values()
|
||||
if isinstance(group, dict)
|
||||
for name in group
|
||||
}
|
||||
function = getattr(node_class, node_class.FUNCTION)
|
||||
accepted = set(inspect.signature(function).parameters)
|
||||
assert declared <= accepted, (
|
||||
node_class.__name__,
|
||||
declared - accepted,
|
||||
)
|
||||
@@ -0,0 +1,62 @@
|
||||
import { app } from "../../../scripts/app.js";
|
||||
|
||||
const LLM_NODE = "PromptGenerateAPI";
|
||||
const SAFE_SOURCE = "Provider environment variable";
|
||||
const NO_KEY_SOURCE = "No key (loopback custom endpoint only)";
|
||||
const SAFE_SOURCES = new Set([SAFE_SOURCE, NO_KEY_SOURCE]);
|
||||
const CREDENTIAL_WIDGET_INDEX = 2;
|
||||
|
||||
function visitGraphNodes(graphData, callback) {
|
||||
for (const node of graphData?.nodes ?? []) {
|
||||
callback(node);
|
||||
}
|
||||
for (const subgraph of graphData?.definitions?.subgraphs ?? []) {
|
||||
visitGraphNodes(subgraph, callback);
|
||||
}
|
||||
}
|
||||
|
||||
function scrubSerializedNode(node) {
|
||||
if (node?.type !== LLM_NODE) {
|
||||
return;
|
||||
}
|
||||
const values = node.widgets_values;
|
||||
if (Array.isArray(values)) {
|
||||
const saved = values[CREDENTIAL_WIDGET_INDEX];
|
||||
if (!SAFE_SOURCES.has(saved)) {
|
||||
values[CREDENTIAL_WIDGET_INDEX] = SAFE_SOURCE;
|
||||
}
|
||||
return;
|
||||
}
|
||||
if (values && typeof values === "object") {
|
||||
// Some frontend versions serialize widgets by name.
|
||||
delete values.api_key;
|
||||
if (!SAFE_SOURCES.has(values.credential_source)) {
|
||||
values.credential_source = SAFE_SOURCE;
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
function enforceLiveWidget(node) {
|
||||
if (node?.type !== LLM_NODE) {
|
||||
return;
|
||||
}
|
||||
const widget = node.widgets?.find(
|
||||
(item) => item.name === "credential_source",
|
||||
);
|
||||
if (widget && !SAFE_SOURCES.has(widget.value)) {
|
||||
widget.value = SAFE_SOURCE;
|
||||
widget.callback?.(SAFE_SOURCE);
|
||||
}
|
||||
}
|
||||
|
||||
app.registerExtension({
|
||||
name: "gokayfem.vlm.api-credential-security",
|
||||
async beforeConfigureGraph(graphData) {
|
||||
// Runs on the cloned workflow before LiteGraph creates any widgets, so a
|
||||
// legacy key never reaches a DOM input or the active graph.
|
||||
visitGraphNodes(graphData, scrubSerializedNode);
|
||||
},
|
||||
loadedGraphNode(node) {
|
||||
enforceLiveWidget(node);
|
||||
},
|
||||
});
|
||||
@@ -0,0 +1,58 @@
|
||||
import { app } from "../../../scripts/app.js";
|
||||
|
||||
const OUTPUT_NAME = "formatted_text";
|
||||
|
||||
function ensureOutputWidget(node) {
|
||||
let widget = node.widgets?.find((item) => item.name === OUTPUT_NAME);
|
||||
if (!widget) {
|
||||
const output = document.createElement("textarea");
|
||||
output.readOnly = true;
|
||||
output.setAttribute("aria-label", "Formatted JSON text output");
|
||||
Object.assign(output.style, {
|
||||
width: "100%",
|
||||
height: "100%",
|
||||
minHeight: "120px",
|
||||
resize: "vertical",
|
||||
boxSizing: "border-box",
|
||||
color: "var(--input-text, #ddd)",
|
||||
background: "var(--comfy-input-bg, #202020)",
|
||||
border: "1px solid var(--border-color, #555)",
|
||||
borderRadius: "6px",
|
||||
padding: "8px",
|
||||
});
|
||||
widget = node.addDOMWidget(OUTPUT_NAME, "STRING", output, {
|
||||
serialize: false,
|
||||
hideOnZoom: false,
|
||||
});
|
||||
widget.serialize = false;
|
||||
widget.inputEl = output;
|
||||
}
|
||||
return widget;
|
||||
}
|
||||
|
||||
app.registerExtension({
|
||||
name: "gokayfem.vlm.json-to-text",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData) {
|
||||
if (nodeData.name !== "JsonToText") {
|
||||
return;
|
||||
}
|
||||
const onCreated = nodeType.prototype.onNodeCreated;
|
||||
nodeType.prototype.onNodeCreated = function (...args) {
|
||||
const result = onCreated?.apply(this, args);
|
||||
ensureOutputWidget(this);
|
||||
return result;
|
||||
};
|
||||
const onExecuted = nodeType.prototype.onExecuted;
|
||||
nodeType.prototype.onExecuted = function (message) {
|
||||
const result = onExecuted?.apply(this, arguments);
|
||||
const values = Array.isArray(message?.text)
|
||||
? message.text
|
||||
: [message?.text ?? ""];
|
||||
const widget = ensureOutputWidget(this);
|
||||
widget.value = values.join("");
|
||||
widget.inputEl.value = widget.value;
|
||||
this.setDirtyCanvas?.(true, true);
|
||||
return result;
|
||||
};
|
||||
},
|
||||
});
|
||||
@@ -0,0 +1,57 @@
|
||||
import { app } from "../../../scripts/app.js";
|
||||
|
||||
function firstValue(value) {
|
||||
return Array.isArray(value) && value.length === 1 ? value[0] : value;
|
||||
}
|
||||
|
||||
app.registerExtension({
|
||||
name: "gokayfem.vlm.play-music",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData) {
|
||||
if (nodeData.name !== "PlayMusic") {
|
||||
return;
|
||||
}
|
||||
const onExecuted = nodeType.prototype.onExecuted;
|
||||
nodeType.prototype.onExecuted = async function (message) {
|
||||
onExecuted?.apply(this, arguments);
|
||||
const mode = firstValue(this.widgets?.[0]?.value) ?? "always";
|
||||
if (mode === "on empty queue" && (app.ui?.lastQueueSize ?? 0) > 0) {
|
||||
return;
|
||||
}
|
||||
|
||||
const raw = firstValue(message?.a);
|
||||
const samples = Array.isArray(raw?.[0]) ? raw[0] : raw;
|
||||
const sampleRate = Number(firstValue(message?.b));
|
||||
if (!samples?.length || !Number.isFinite(sampleRate)) {
|
||||
return;
|
||||
}
|
||||
|
||||
this.__vlmAudioSource?.stop?.();
|
||||
const AudioContext = window.AudioContext ?? window.webkitAudioContext;
|
||||
this.__vlmAudioContext ??= new AudioContext({ sampleRate });
|
||||
await this.__vlmAudioContext.resume();
|
||||
const buffer = this.__vlmAudioContext.createBuffer(
|
||||
1,
|
||||
samples.length,
|
||||
sampleRate,
|
||||
);
|
||||
buffer.getChannelData(0).set(samples);
|
||||
const source = this.__vlmAudioContext.createBufferSource();
|
||||
const gain = this.__vlmAudioContext.createGain();
|
||||
gain.gain.value = Number(firstValue(this.widgets?.[1]?.value) ?? 0.5);
|
||||
source.buffer = buffer;
|
||||
source.connect(gain);
|
||||
gain.connect(this.__vlmAudioContext.destination);
|
||||
source.start();
|
||||
this.__vlmAudioSource = source;
|
||||
};
|
||||
|
||||
const onRemoved = nodeType.prototype.onRemoved;
|
||||
nodeType.prototype.onRemoved = function (...args) {
|
||||
this.__vlmAudioSource?.stop?.();
|
||||
void this.__vlmAudioContext?.close?.();
|
||||
this.__vlmAudioSource = null;
|
||||
this.__vlmAudioContext = null;
|
||||
return onRemoved?.apply(this, args);
|
||||
};
|
||||
},
|
||||
});
|
||||
@@ -0,0 +1,270 @@
|
||||
import { app } from "../../../scripts/app.js";
|
||||
import { api } from "../../../scripts/api.js";
|
||||
|
||||
const OUTPUT_NAME = "output_text";
|
||||
const VIEW_TEXT_NODE = "ViewText";
|
||||
const STREAMING_SOURCE_NODES = new Set([
|
||||
"ModernVLM",
|
||||
"Moondream31Query",
|
||||
"Moondream31Caption",
|
||||
"PromptGenerateAPI",
|
||||
"HostedVLMAPI",
|
||||
"VLMVideoTemporalReasoner",
|
||||
]);
|
||||
|
||||
function textMetrics(value) {
|
||||
const text = String(value ?? "");
|
||||
const words = text.trim() ? text.trim().split(/\s+/u).length : 0;
|
||||
const lines = text ? text.split("\n").length : 0;
|
||||
return `${text.length.toLocaleString()} chars · ${words.toLocaleString()} words · ${lines.toLocaleString()} lines`;
|
||||
}
|
||||
|
||||
function makeButton(label, title, handler) {
|
||||
const button = document.createElement("button");
|
||||
button.textContent = label;
|
||||
button.type = "button";
|
||||
button.title = title;
|
||||
button.addEventListener("click", handler);
|
||||
Object.assign(button.style, {
|
||||
color: "var(--input-text, #ddd)",
|
||||
background: "var(--comfy-input-bg, #202020)",
|
||||
border: "1px solid var(--border-color, #555)",
|
||||
borderRadius: "5px",
|
||||
padding: "3px 8px",
|
||||
cursor: "pointer",
|
||||
whiteSpace: "nowrap",
|
||||
});
|
||||
return button;
|
||||
}
|
||||
|
||||
function ensureOutputWidget(node) {
|
||||
let widget = node.widgets?.find((item) => item.name === OUTPUT_NAME);
|
||||
if (widget) {
|
||||
return widget;
|
||||
}
|
||||
|
||||
const container = document.createElement("div");
|
||||
const header = document.createElement("div");
|
||||
const status = document.createElement("span");
|
||||
const meta = document.createElement("span");
|
||||
const actions = document.createElement("div");
|
||||
const output = document.createElement("textarea");
|
||||
|
||||
status.textContent = "Ready";
|
||||
meta.textContent = textMetrics("");
|
||||
output.readOnly = true;
|
||||
output.wrap = "soft";
|
||||
output.spellcheck = false;
|
||||
output.setAttribute("aria-label", "VLM text output");
|
||||
|
||||
const copy = makeButton("Copy", "Copy complete text", async () => {
|
||||
const previous = copy.textContent;
|
||||
try {
|
||||
await navigator.clipboard.writeText(output.value);
|
||||
copy.textContent = "Copied";
|
||||
} catch {
|
||||
copy.textContent = "Copy failed";
|
||||
}
|
||||
window.setTimeout(() => {
|
||||
copy.textContent = previous;
|
||||
}, 1200);
|
||||
});
|
||||
const download = makeButton("Save", "Download output as a UTF-8 text file", () => {
|
||||
const blob = new Blob([output.value], {
|
||||
type: "text/plain;charset=utf-8",
|
||||
});
|
||||
const url = URL.createObjectURL(blob);
|
||||
const anchor = document.createElement("a");
|
||||
anchor.href = url;
|
||||
anchor.download = `vlm-output-${new Date().toISOString().replaceAll(":", "-")}.txt`;
|
||||
anchor.click();
|
||||
URL.revokeObjectURL(url);
|
||||
});
|
||||
const wrap = makeButton("Wrap: on", "Toggle long-line wrapping", () => {
|
||||
const enabled = output.wrap !== "off";
|
||||
output.wrap = enabled ? "off" : "soft";
|
||||
output.style.whiteSpace = enabled ? "pre" : "pre-wrap";
|
||||
output.style.overflowX = enabled ? "auto" : "hidden";
|
||||
wrap.textContent = enabled ? "Wrap: off" : "Wrap: on";
|
||||
});
|
||||
const follow = makeButton("Follow: on", "Follow streaming output", () => {
|
||||
widget.followOutput = !widget.followOutput;
|
||||
follow.textContent = widget.followOutput ? "Follow: on" : "Follow: off";
|
||||
});
|
||||
|
||||
actions.append(wrap, follow, copy, download);
|
||||
header.append(status, meta, actions);
|
||||
container.append(header, output);
|
||||
|
||||
Object.assign(container.style, {
|
||||
display: "flex",
|
||||
flexDirection: "column",
|
||||
width: "100%",
|
||||
height: "100%",
|
||||
minHeight: "190px",
|
||||
gap: "6px",
|
||||
});
|
||||
Object.assign(header.style, {
|
||||
display: "grid",
|
||||
gridTemplateColumns: "auto minmax(0, 1fr) auto",
|
||||
alignItems: "center",
|
||||
gap: "9px",
|
||||
color: "var(--descrip-text, #aaa)",
|
||||
fontSize: "11px",
|
||||
});
|
||||
Object.assign(meta.style, {
|
||||
overflow: "hidden",
|
||||
textOverflow: "ellipsis",
|
||||
whiteSpace: "nowrap",
|
||||
});
|
||||
Object.assign(actions.style, {
|
||||
display: "flex",
|
||||
gap: "4px",
|
||||
justifyContent: "flex-end",
|
||||
});
|
||||
Object.assign(output.style, {
|
||||
width: "100%",
|
||||
flex: "1",
|
||||
minHeight: "160px",
|
||||
resize: "vertical",
|
||||
boxSizing: "border-box",
|
||||
color: "var(--input-text, #ddd)",
|
||||
background: "var(--comfy-input-bg, #202020)",
|
||||
border: "1px solid var(--border-color, #555)",
|
||||
borderRadius: "6px",
|
||||
padding: "9px",
|
||||
lineHeight: "1.45",
|
||||
whiteSpace: "pre-wrap",
|
||||
overflowWrap: "anywhere",
|
||||
tabSize: "4",
|
||||
});
|
||||
|
||||
widget = node.addDOMWidget(OUTPUT_NAME, "STRING", container, {
|
||||
serialize: false,
|
||||
hideOnZoom: false,
|
||||
});
|
||||
widget.serialize = false;
|
||||
widget.inputEl = output;
|
||||
widget.statusEl = status;
|
||||
widget.metaEl = meta;
|
||||
widget.followOutput = true;
|
||||
return widget;
|
||||
}
|
||||
|
||||
function setOutput(node, text, state = "Complete") {
|
||||
const widget = ensureOutputWidget(node);
|
||||
const value = Array.isArray(text) ? text.join("\n\n") : String(text ?? "");
|
||||
widget.value = value;
|
||||
widget.inputEl.value = value;
|
||||
widget.statusEl.textContent = state;
|
||||
widget.metaEl.textContent = textMetrics(value);
|
||||
if (widget.followOutput && state === "Streaming…") {
|
||||
widget.inputEl.scrollTop = widget.inputEl.scrollHeight;
|
||||
}
|
||||
node.setDirtyCanvas?.(true, true);
|
||||
}
|
||||
|
||||
function findNode(graph, id) {
|
||||
if (!graph || id == null) {
|
||||
return null;
|
||||
}
|
||||
return graph.getNodeById?.(id)
|
||||
?? graph.getNodeById?.(String(id))
|
||||
?? graph.getNodeById?.(Number(id))
|
||||
?? null;
|
||||
}
|
||||
|
||||
function linkFor(graph, linkId) {
|
||||
return graph?.links?.get?.(linkId)
|
||||
?? graph?._links?.get?.(linkId)
|
||||
?? null;
|
||||
}
|
||||
|
||||
function isReroute(node) {
|
||||
return String(node?.type ?? "").toLowerCase().includes("reroute");
|
||||
}
|
||||
|
||||
function connectedViewTextNodes(source) {
|
||||
if (!source?.graph) {
|
||||
return [];
|
||||
}
|
||||
const found = new Set();
|
||||
const visited = new Set([source.id]);
|
||||
const queue = [source];
|
||||
while (queue.length) {
|
||||
const current = queue.shift();
|
||||
for (const output of current.outputs ?? []) {
|
||||
for (const linkId of output.links ?? []) {
|
||||
const link = linkFor(source.graph, linkId);
|
||||
const target = findNode(source.graph, link?.target_id);
|
||||
if (!target || visited.has(target.id)) {
|
||||
continue;
|
||||
}
|
||||
visited.add(target.id);
|
||||
if (target.type === VIEW_TEXT_NODE) {
|
||||
found.add(target);
|
||||
} else if (isReroute(target)) {
|
||||
queue.push(target);
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
return [...found];
|
||||
}
|
||||
|
||||
function updateFromProgress({ nodeId, text }) {
|
||||
const source = findNode(app.rootGraph ?? app.graph, nodeId);
|
||||
if (!source) {
|
||||
return;
|
||||
}
|
||||
if (source.type === VIEW_TEXT_NODE) {
|
||||
setOutput(source, text, "Streaming…");
|
||||
return;
|
||||
}
|
||||
if (!STREAMING_SOURCE_NODES.has(source.type)) {
|
||||
return;
|
||||
}
|
||||
for (const target of connectedViewTextNodes(source)) {
|
||||
setOutput(target, text, "Streaming…");
|
||||
}
|
||||
}
|
||||
|
||||
app.registerExtension({
|
||||
name: "gokayfem.vlm.view-text",
|
||||
async setup() {
|
||||
api.addEventListener("progress_text", ({ detail }) => {
|
||||
updateFromProgress(detail ?? {});
|
||||
});
|
||||
},
|
||||
async beforeRegisterNodeDef(nodeType, nodeData) {
|
||||
if (nodeData.name !== VIEW_TEXT_NODE) {
|
||||
return;
|
||||
}
|
||||
const onCreated = nodeType.prototype.onNodeCreated;
|
||||
nodeType.prototype.onNodeCreated = function (...args) {
|
||||
const result = onCreated?.apply(this, args);
|
||||
ensureOutputWidget(this);
|
||||
if (Array.isArray(this.size)) {
|
||||
this.setSize?.([
|
||||
Math.max(this.size[0], 430),
|
||||
Math.max(this.size[1], 290),
|
||||
]);
|
||||
}
|
||||
return result;
|
||||
};
|
||||
const onExecuted = nodeType.prototype.onExecuted;
|
||||
nodeType.prototype.onExecuted = function (message) {
|
||||
const result = onExecuted?.apply(this, arguments);
|
||||
setOutput(this, message?.text, "Complete");
|
||||
return result;
|
||||
};
|
||||
},
|
||||
onNodeOutputsUpdated(nodeOutputs) {
|
||||
for (const [nodeId, output] of Object.entries(nodeOutputs ?? {})) {
|
||||
const node = findNode(app.rootGraph ?? app.graph, nodeId);
|
||||
if (node?.type === VIEW_TEXT_NODE && output?.text != null) {
|
||||
setOutput(node, output.text, "Complete");
|
||||
}
|
||||
}
|
||||
},
|
||||
});
|
||||
Reference in New Issue
Block a user