Compare commits
177
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 gokayfem |
94cb521903 | ||
|
gokayfem
|
d627aa5eda | ||
|
gokayfem
|
7bfc87bc04 | ||
|
gokayfem
|
456387f7e0 | ||
|
gokayfem
|
d9584e1e35 | ||
|
gokayfem
|
858a4a4998 | ||
|
gokayfem
|
b0e1d75f96 | ||
|
gokayfem
|
78d321951d | ||
|
gokayfem
|
f68175e369 | ||
|
gokayfem
|
3f9612774e | ||
|
gokayfem
|
7a74f5a079 | ||
|
Gökay Aydoğan
|
67344abe6a | ||
|
octo-patch
|
e79f316908 | ||
|
Gökay Aydoğan
|
f4bc8b9eef | ||
|
gokayfem
|
5779c50b20 | ||
|
gokayfem
|
48101541a3 | ||
|
Gökay Aydoğan
|
fcfdf7b210 | ||
|
dependabot[bot]
|
56cdd25aa9 | ||
|
gokayfem
|
9aeca11c35 | ||
|
gokayfem
|
79a929c1ca | ||
|
Gokay Aydogan
|
e2b20cde13 | ||
|
Gokay Aydogan
|
04275b57cb | ||
|
Gokay Aydogan
|
2e41de6ac2 | ||
|
Gokay Aydogan
|
8b4226474a | ||
|
Gokay Aydogan
|
8a432184d3 | ||
|
Gokay Aydogan
|
da5f4d5787 | ||
|
Gokay Aydogan
|
45d21d0642 | ||
|
Gokay Aydogan
|
8e55c81b34 | ||
|
Gökay Aydoğan
|
f06a2a3e6c | ||
|
Gokay Aydogan
|
c13ee2364e | ||
|
gokayfem
|
b8ae298abf | ||
|
Gökay Aydoğan
|
bb7d51777c | ||
|
gokayfem
|
102f1662ac | ||
|
Gökay Aydoğan
|
44fefcb57a | ||
|
Gökay Aydoğan
|
505b324f66 | ||
|
Gökay Aydoğan
|
39fc116341 | ||
|
gokayfem
|
239c9045ab | ||
|
gokayfem
|
0da5070039 | ||
|
gokayfem
|
4c200c4dda | ||
|
gokayfem
|
58fd4823b9 | ||
|
gokayfem
|
2efd3631b8 | ||
|
gokayfem
|
bcb756d973 | ||
|
gokayfem
|
37317a8478 | ||
|
gokayfem
|
460b27a1b5 | ||
|
gokayfem
|
1e04a56444 | ||
|
gokayfem
|
b89f6288bb | ||
|
Gökay Aydoğan
|
066b10fd60 | ||
|
Gökay Aydoğan
|
eabca719dd | ||
|
Gökay Aydoğan
|
8bd18dd52b | ||
|
mavibirdesmi
|
858ab8a13e | ||
|
Gökay Aydoğan
|
1ca496c1c8 | ||
|
Juggernaut
|
7174a2ac91 | ||
|
Juggernaut
|
77f70e4417 | ||
|
Gökay Aydoğan
|
320cf09f6c | ||
|
Gökay Aydoğan
|
59ead9f513 | ||
|
EnragedAntelope
|
6817bdba01 | ||
|
EnragedAntelope
|
724a787eae | ||
|
EnragedAntelope
|
7f5bc8956b | ||
|
Gökay Aydoğan
|
52e20049e8 | ||
|
Gökay Aydoğan
|
babc604703 | ||
|
EnragedAntelope
|
83ce962b94 | ||
|
EnragedAntelope
|
cf463e3590 | ||
|
EnragedAntelope
|
d977b2c106 | ||
|
gokayfem
|
0bfaad3a91 | ||
|
gokayfem
|
bfa702a282 | ||
|
gokayfem
|
e1a48dbaa4 | ||
|
gokayfem
|
7817b69fe3 | ||
|
Gökay Aydoğan
|
bd8975fbdc | ||
|
Gökay Aydoğan
|
b09fdb6e02 | ||
|
Gökay Aydoğan
|
372a8448f6 | ||
|
gokayfem
|
63e9e20625 | ||
|
Gökay Aydoğan
|
80d1f30a99 | ||
|
Gökay Aydoğan
|
1cc82e14b5 | ||
|
Gökay Aydoğan
|
68b8966f1b | ||
|
gokayfem
|
f260a590ba | ||
|
Gökay Aydoğan
|
27f72e532a | ||
|
gokayfem
|
4469d7a19f | ||
|
EnragedAntelope
|
a8f60dd44f | ||
|
EnragedAntelope
|
eccdb0e0d4 | ||
|
EnragedAntelope
|
1cf85b8f63 | ||
|
Gökay Aydoğan
|
a5ceb90f48 | ||
|
EnragedAntelope
|
9723f506a3 | ||
|
EnragedAntelope
|
40f25f55aa | ||
|
Gökay Aydoğan
|
400fded7af | ||
|
EnragedAntelope
|
6d76b29f71 | ||
|
Gökay Aydoğan
|
043dfbe727 | ||
|
Gökay Aydoğan
|
57d6060cd1 | ||
|
default
|
3df8e96adf | ||
|
Gökay Aydoğan
|
aee755b26a | ||
|
Gökay Aydoğan
|
8506a8e1f2 | ||
|
Yoland Yan
|
12b550516e | ||
|
Yoland Yan
|
04fec51386 | ||
|
Gökay Aydoğan
|
a3caf32dba | ||
|
Gökay Aydoğan
|
711801166b | ||
|
snomiao
|
f45e1456ee | ||
|
Gökay Aydoğan
|
260316eacb | ||
|
Gökay Aydoğan
|
d6bb765089 | ||
|
Gökay Aydoğan
|
7979ae79a9 | ||
|
Gökay Aydoğan
|
ab0ea30a11 | ||
|
gokayfem
|
114e71d4c2 | ||
|
gokayfem
|
2d289c3c9f | ||
|
Gökay Aydoğan
|
fc5ddf6d05 | ||
|
Gökay Aydoğan
|
f5e3a896e9 | ||
|
Gökay Aydoğan
|
5a4f077c60 | ||
|
haohaocreates
|
81bee12a68 | ||
|
Gökay Aydoğan
|
e2c711422e | ||
|
Gökay Aydoğan
|
69a774f786 | ||
|
Gökay Aydoğan
|
95b2d039fd | ||
|
Gökay Aydoğan
|
3636697f2f | ||
|
haohaocreates
|
ebb34be2cc | ||
|
null
|
431f2623c3 | ||
|
Wouter de Bie
|
546164cc5e | ||
|
Gökay Aydoğan
|
abb2838db1 | ||
|
gokayfem
|
3836e67cd1 | ||
|
Torbjörn Lönnemark
|
5b46de997c | ||
|
gokayfem
|
ebceeac0ee | ||
|
gokayfem
|
c094952b51 | ||
|
gokayfem
|
54b5c1024e | ||
|
SKB
|
bea554556a | ||
|
SKB
|
a4f1223689 | ||
|
SKB
|
ff3814fc5a | ||
|
gokayfem
|
d1770aa931 | ||
|
gokayfem
|
af77cc2790 | ||
|
gokayfem
|
fe20baaa2d | ||
|
gokayfem
|
a8aa176fb5 | ||
|
gokayfem
|
26bd276105 | ||
|
gokayfem
|
c202ae481c | ||
|
gokayfem
|
684f05f012 | ||
|
gokayfem
|
ad7398467d | ||
|
gokayfem
|
8f918d07db | ||
|
gokayfem
|
e04019e22b | ||
|
gokayfem
|
21c13d8232 | ||
|
gokayfem
|
873ccd3d6b | ||
|
gokayfem
|
e352ff52b6 | ||
|
gokayfem
|
6600b13f9e | ||
|
gokayfem
|
470b347c48 | ||
|
gokayfem
|
1fe7a608d6 | ||
|
gokayfem
|
4048e74841 | ||
|
gokayfem
|
5bc422b372 | ||
|
gokayfem
|
3d72d9bbd1 | ||
|
gokayfem
|
a363153eb5 | ||
|
gokayfem
|
6e043f44f6 | ||
|
gokayfem
|
12dff74965 | ||
|
gokayfem
|
ab0ff641e8 | ||
|
gokayfem
|
ae9ef30c4c | ||
|
gokayfem
|
6d2c2f84d8 | ||
|
gokayfem
|
70bdb2b883 | ||
|
gokayfem
|
6765b6ea11 | ||
|
gokayfem
|
cac0f8d22a | ||
|
gokayfem
|
fc88d71179 | ||
|
gokayfem
|
39885c9246 | ||
|
gokayfem
|
640fb70f33 | ||
|
gokayfem
|
5dee27bd9b | ||
|
gokayfem
|
dc262a9683 | ||
|
gokayfem
|
3a95355d05 | ||
|
gokayfem
|
e452c0ea91 | ||
|
gokayfem
|
1444dbb346 | ||
|
gokayfem
|
899b894435 | ||
|
gokayfem
|
c2850d8e7a | ||
|
gokayfem
|
a829cf4932 | ||
|
gokayfem
|
64da5b1506 | ||
|
gokayfem
|
f1438415f7 | ||
|
gokayfem
|
fd65743f13 | ||
|
gokayfem
|
777933600e | ||
|
gokayfem
|
6f9b156f24 | ||
|
gokayfem
|
08c743d2ae | ||
|
gokayfem
|
c920a4e714 | ||
|
gokayfem
|
9d15d4567b | ||
|
gokayfem
|
f091d411f7 | ||
|
gokayfem
|
ce9abb3bd9 | ||
|
gokayfem
|
16eb505136 | ||
|
gokayfem
|
4de8baaaaf | ||
|
gokayfem
|
b57aa3ada9 | ||
|
gokayfem
|
b22479ac71 | ||
|
gokayfem
|
9c6aef69a0 | ||
|
gokayfem
|
8d4c8549c6 | ||
|
gokayfem
|
3d03ddeb9c |
@@ -0,0 +1,104 @@
|
||||
name: Bug report
|
||||
description: A node fails, errors, or produces wrong output.
|
||||
labels: ["bug"]
|
||||
body:
|
||||
- type: markdown
|
||||
attributes:
|
||||
value: |
|
||||
Most unresolvable reports are missing the environment details below.
|
||||
Please run the **VLM Runtime Diagnostics** node and paste its output —
|
||||
it captures your OS, Python, PyTorch, accelerator backend, and which
|
||||
optional backends are installed.
|
||||
|
||||
- type: input
|
||||
id: version
|
||||
attributes:
|
||||
label: Node pack version
|
||||
description: From ComfyUI Manager, or the `version` in `pyproject.toml`.
|
||||
placeholder: "3.3.1"
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: dropdown
|
||||
id: install
|
||||
attributes:
|
||||
label: How did you install it?
|
||||
options:
|
||||
- ComfyUI Manager
|
||||
- Comfy Registry
|
||||
- git clone into custom_nodes
|
||||
- Other (describe below)
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: dropdown
|
||||
id: comfy
|
||||
attributes:
|
||||
label: ComfyUI flavour
|
||||
options:
|
||||
- ComfyUI Desktop
|
||||
- ComfyUI Portable (python_embeded)
|
||||
- Manual install (venv)
|
||||
- Manual install (conda)
|
||||
- Cloud / RunPod / other host
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: textarea
|
||||
id: diagnostics
|
||||
attributes:
|
||||
label: VLM Runtime Diagnostics output
|
||||
description: Add the node to any workflow, run it, and paste the result.
|
||||
render: text
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: input
|
||||
id: node
|
||||
attributes:
|
||||
label: Which node fails?
|
||||
placeholder: "LLMSampler, LLavaSamplerSimple, ModernVLM, ..."
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: input
|
||||
id: model
|
||||
attributes:
|
||||
label: Which model / GGUF file?
|
||||
description: Include the exact filename or Hugging Face repo id.
|
||||
placeholder: "Qwen 3 VL 4B Instruct, or llava-1.6-mistral-7b.Q4_K_M.gguf"
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: textarea
|
||||
id: expected
|
||||
attributes:
|
||||
label: What did you expect, and what happened instead?
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: textarea
|
||||
id: traceback
|
||||
attributes:
|
||||
label: Full console output
|
||||
description: |
|
||||
The complete traceback from the ComfyUI terminal, not just the last
|
||||
line. Include the startup log if the pack failed to import.
|
||||
render: shell
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: checkboxes
|
||||
id: checks
|
||||
attributes:
|
||||
label: Before submitting
|
||||
options:
|
||||
- label: I updated to the latest version of this node pack and ComfyUI.
|
||||
required: true
|
||||
- label: I searched existing open and closed issues.
|
||||
required: true
|
||||
- label: >-
|
||||
If this involves GGUF or `llama-cpp-python`, I installed it with
|
||||
the arguments for my accelerator from the
|
||||
[llama-cpp-python install guide](https://github.com/abetlen/llama-cpp-python#installation).
|
||||
required: false
|
||||
@@ -0,0 +1,11 @@
|
||||
blank_issues_enabled: false
|
||||
contact_links:
|
||||
- name: llama-cpp-python installation help
|
||||
url: https://github.com/abetlen/llama-cpp-python#installation
|
||||
about: >-
|
||||
Build or GPU-offload failures for GGUF nodes are almost always
|
||||
llama-cpp-python installation issues. Install the wheel matching your
|
||||
accelerator first.
|
||||
- name: ComfyUI Manager and installation problems
|
||||
url: https://github.com/Comfy-Org/ComfyUI-Manager/issues
|
||||
about: For problems installing or updating custom nodes in general.
|
||||
@@ -0,0 +1,46 @@
|
||||
name: Model or feature request
|
||||
description: Ask for support for a new VLM/LLM, or a new node.
|
||||
labels: ["enhancement"]
|
||||
body:
|
||||
- type: textarea
|
||||
id: what
|
||||
attributes:
|
||||
label: What would you like added?
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: input
|
||||
id: model
|
||||
attributes:
|
||||
label: Model repository (if requesting a model)
|
||||
description: A Hugging Face repo id, so the architecture can be checked.
|
||||
placeholder: "Qwen/Qwen3-VL-8B-Instruct"
|
||||
|
||||
- type: dropdown
|
||||
id: backend
|
||||
attributes:
|
||||
label: Which backend would it use?
|
||||
options:
|
||||
- transformers (safetensors)
|
||||
- llama.cpp (GGUF)
|
||||
- Hosted API
|
||||
- Not sure
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: textarea
|
||||
id: why
|
||||
attributes:
|
||||
label: What does it let you do that current nodes cannot?
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: checkboxes
|
||||
id: checks
|
||||
attributes:
|
||||
label: Before submitting
|
||||
options:
|
||||
- label: >-
|
||||
I checked the README node reference to confirm this is not already
|
||||
supported.
|
||||
required: true
|
||||
@@ -0,0 +1,33 @@
|
||||
## What does this change?
|
||||
|
||||
<!-- One or two sentences. Link any issue it closes: "Closes #123". -->
|
||||
|
||||
## Type of change
|
||||
|
||||
- [ ] Bug fix
|
||||
- [ ] New model support
|
||||
- [ ] New node
|
||||
- [ ] Refactor / maintenance
|
||||
- [ ] Documentation
|
||||
|
||||
## Checklist
|
||||
|
||||
- [ ] `python -m pytest -q` passes.
|
||||
- [ ] `python -m ruff check .` passes.
|
||||
- [ ] Importing the pack still performs no network access, compilation, or
|
||||
package install.
|
||||
- [ ] If a node schema changed, existing widget order is preserved (Comfy
|
||||
serializes widget values by position, so reordering breaks saved
|
||||
workflows).
|
||||
- [ ] New optional dependencies fail only the node that needs them, with an
|
||||
actionable error.
|
||||
- [ ] `pyproject.toml` `version` is bumped if this is user-visible, and
|
||||
`CHANGELOG.md` has an entry. Releases only publish on a version change.
|
||||
|
||||
## Testing
|
||||
|
||||
<!--
|
||||
Which nodes did you run, on which backend (CUDA / ROCm / Metal / XPU / CPU),
|
||||
and with which model? Real-weight checks are opt-in:
|
||||
python tests/manual_model_smoke.py --model "Qwen 3 VL 4B Instruct"
|
||||
-->
|
||||
@@ -0,0 +1,14 @@
|
||||
version: 2
|
||||
updates:
|
||||
# Action versions only. Python dependency ranges are deliberately loose
|
||||
# because ComfyUI owns torch, numpy, and Pillow in the shared environment.
|
||||
- package-ecosystem: github-actions
|
||||
directory: "/"
|
||||
schedule:
|
||||
interval: monthly
|
||||
open-pull-requests-limit: 5
|
||||
commit-message:
|
||||
prefix: "ci"
|
||||
groups:
|
||||
actions:
|
||||
patterns: ["*"]
|
||||
@@ -0,0 +1,96 @@
|
||||
name: CI
|
||||
|
||||
on:
|
||||
push:
|
||||
pull_request:
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
lint:
|
||||
name: Lint
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
- uses: actions/setup-python@v7
|
||||
with:
|
||||
python-version: "3.12"
|
||||
cache: pip
|
||||
cache-dependency-path: requirements-dev.txt
|
||||
- name: Install lint tooling
|
||||
run: python -m pip install -r requirements-dev.txt
|
||||
- name: Ruff
|
||||
run: python -m ruff check --output-format github .
|
||||
|
||||
test:
|
||||
name: ${{ matrix.label }}
|
||||
runs-on: ${{ matrix.os }}
|
||||
timeout-minutes: 35
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
include:
|
||||
- label: Linux / Python 3.10
|
||||
os: ubuntu-latest
|
||||
python: "3.10"
|
||||
cpu_index: true
|
||||
coverage: false
|
||||
- label: Linux / Python 3.13
|
||||
os: ubuntu-latest
|
||||
python: "3.13"
|
||||
cpu_index: true
|
||||
coverage: true
|
||||
- label: Windows / Python 3.12
|
||||
os: windows-latest
|
||||
python: "3.12"
|
||||
cpu_index: true
|
||||
coverage: false
|
||||
- label: macOS / Python 3.12
|
||||
os: macos-14
|
||||
python: "3.12"
|
||||
cpu_index: false
|
||||
coverage: false
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
- uses: actions/setup-python@v7
|
||||
with:
|
||||
python-version: ${{ matrix.python }}
|
||||
cache: pip
|
||||
cache-dependency-path: requirements.txt
|
||||
- name: Install CPU PyTorch
|
||||
if: matrix.cpu_index == true
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install torch --index-url https://download.pytorch.org/whl/cpu
|
||||
- name: Install macOS PyTorch
|
||||
if: matrix.cpu_index == false
|
||||
run: |
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install torch
|
||||
- name: Install ComfyUI and node dependencies
|
||||
run: |
|
||||
git clone --depth 1 https://github.com/Comfy-Org/ComfyUI.git ../ComfyUI
|
||||
python -m pip install -r requirements-dev.txt
|
||||
python -m pip install -r ../ComfyUI/requirements.txt -r requirements.txt
|
||||
- name: Test
|
||||
if: matrix.coverage == false
|
||||
run: python -m pytest -q
|
||||
- name: Test with coverage
|
||||
if: matrix.coverage == true
|
||||
run: >-
|
||||
python -m pytest -q
|
||||
--cov=nodes --cov-report=term-missing:skip-covered
|
||||
--cov-report=xml --cov-fail-under=70
|
||||
- name: Upload coverage report
|
||||
if: matrix.coverage == true && always()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: coverage-xml
|
||||
path: coverage.xml
|
||||
if-no-files-found: warn
|
||||
- name: Compile
|
||||
run: python -m compileall -q .
|
||||
- name: Build distribution
|
||||
run: python -m build
|
||||
@@ -0,0 +1,171 @@
|
||||
name: Publish Comfy node fleet
|
||||
|
||||
on:
|
||||
workflow_dispatch:
|
||||
inputs:
|
||||
target:
|
||||
description: Node repository to check
|
||||
required: true
|
||||
default: all
|
||||
type: choice
|
||||
options:
|
||||
- all
|
||||
- vlm
|
||||
- depth
|
||||
- dream
|
||||
- texture
|
||||
schedule:
|
||||
- cron: "17 * * * *"
|
||||
push:
|
||||
branches:
|
||||
- main
|
||||
paths:
|
||||
- ".github/workflows/publish-fleet.yml"
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
concurrency:
|
||||
group: comfy-registry-fleet
|
||||
cancel-in-progress: false
|
||||
|
||||
jobs:
|
||||
publish:
|
||||
name: Check ${{ matrix.target }}
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
include:
|
||||
- target: vlm
|
||||
repository: gokayfem/ComfyUI_VLM_nodes
|
||||
node_id: comfyui_vlm_nodes
|
||||
- target: depth
|
||||
repository: gokayfem/ComfyUI-Depth-Visualization
|
||||
node_id: comfyui-depth-visualization
|
||||
- target: dream
|
||||
repository: gokayfem/ComfyUI-Dream-Interpreter
|
||||
node_id: comfyui-dream-interpreter
|
||||
- target: texture
|
||||
repository: gokayfem/ComfyUI-Texture-Simple
|
||||
node_id: comfyui-texture-simple
|
||||
|
||||
steps:
|
||||
- name: Select target
|
||||
id: select
|
||||
env:
|
||||
REQUESTED_TARGET: ${{ inputs.target || 'all' }}
|
||||
MATRIX_TARGET: ${{ matrix.target }}
|
||||
run: |
|
||||
if [[ "$REQUESTED_TARGET" == "all" || "$REQUESTED_TARGET" == "$MATRIX_TARGET" ]]; then
|
||||
echo "selected=true" >> "$GITHUB_OUTPUT"
|
||||
else
|
||||
echo "selected=false" >> "$GITHUB_OUTPUT"
|
||||
fi
|
||||
|
||||
- name: Check out node
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
uses: actions/checkout@v7
|
||||
with:
|
||||
repository: ${{ matrix.repository }}
|
||||
ref: main
|
||||
path: node
|
||||
persist-credentials: false
|
||||
|
||||
- name: Set up Python
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
uses: actions/setup-python@v7
|
||||
with:
|
||||
python-version: "3.12"
|
||||
|
||||
- name: Read and verify release metadata
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
id: metadata
|
||||
working-directory: node
|
||||
env:
|
||||
EXPECTED_NODE_ID: ${{ matrix.node_id }}
|
||||
run: |
|
||||
python - <<'PY'
|
||||
import os
|
||||
import tomllib
|
||||
from pathlib import Path
|
||||
|
||||
metadata = tomllib.loads(Path("pyproject.toml").read_text(encoding="utf-8"))
|
||||
node_id = metadata["project"]["name"]
|
||||
version = metadata["project"]["version"]
|
||||
publisher = metadata["tool"]["comfy"]["PublisherId"]
|
||||
expected = os.environ["EXPECTED_NODE_ID"]
|
||||
|
||||
if node_id != expected:
|
||||
raise SystemExit(f"Expected node id {expected!r}, found {node_id!r}")
|
||||
if publisher != "gokayfem":
|
||||
raise SystemExit(f"Expected publisher 'gokayfem', found {publisher!r}")
|
||||
|
||||
with Path(os.environ["GITHUB_OUTPUT"]).open("a", encoding="utf-8") as output:
|
||||
print(f"node_id={node_id}", file=output)
|
||||
print(f"version={version}", file=output)
|
||||
PY
|
||||
|
||||
- name: Check Registry version
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
id: registry
|
||||
env:
|
||||
NODE_ID: ${{ steps.metadata.outputs.node_id }}
|
||||
VERSION: ${{ steps.metadata.outputs.version }}
|
||||
run: |
|
||||
python - <<'PY'
|
||||
import json
|
||||
import os
|
||||
import urllib.parse
|
||||
import urllib.request
|
||||
from pathlib import Path
|
||||
|
||||
node_id = urllib.parse.quote(os.environ["NODE_ID"], safe="")
|
||||
url = f"https://api.comfy.org/nodes/{node_id}/versions"
|
||||
request = urllib.request.Request(
|
||||
url,
|
||||
headers={"Accept": "application/json", "User-Agent": "comfy-node-fleet-publisher"},
|
||||
)
|
||||
with urllib.request.urlopen(request, timeout=30) as response:
|
||||
versions = json.load(response)
|
||||
|
||||
wanted = os.environ["VERSION"]
|
||||
exists = any(item.get("version") == wanted for item in versions)
|
||||
with Path(os.environ["GITHUB_OUTPUT"]).open("a", encoding="utf-8") as output:
|
||||
print(f"exists={'true' if exists else 'false'}", file=output)
|
||||
PY
|
||||
|
||||
- name: Require publisher credential
|
||||
if: steps.select.outputs.selected == 'true' && steps.registry.outputs.exists != 'true'
|
||||
env:
|
||||
REGISTRY_ACCESS_TOKEN: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
run: |
|
||||
if [[ -z "$REGISTRY_ACCESS_TOKEN" ]]; then
|
||||
echo "::error title=Missing registry token::Add the publisher API key as the REGISTRY_ACCESS_TOKEN repository secret."
|
||||
exit 1
|
||||
fi
|
||||
|
||||
- name: Install pinned publisher
|
||||
if: steps.select.outputs.selected == 'true' && steps.registry.outputs.exists != 'true'
|
||||
run: python -m pip install --disable-pip-version-check --no-input "comfy-cli==1.13.0"
|
||||
|
||||
- name: Publish missing version
|
||||
if: steps.select.outputs.selected == 'true' && steps.registry.outputs.exists != 'true'
|
||||
working-directory: node
|
||||
env:
|
||||
REGISTRY_ACCESS_TOKEN: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
run: comfy --skip-prompt --no-enable-telemetry node publish --token "$REGISTRY_ACCESS_TOKEN"
|
||||
|
||||
- name: Record result
|
||||
if: steps.select.outputs.selected == 'true'
|
||||
env:
|
||||
NODE_ID: ${{ steps.metadata.outputs.node_id }}
|
||||
VERSION: ${{ steps.metadata.outputs.version }}
|
||||
ALREADY_PUBLISHED: ${{ steps.registry.outputs.exists }}
|
||||
run: |
|
||||
if [[ "$ALREADY_PUBLISHED" == "true" ]]; then
|
||||
echo "### $NODE_ID $VERSION already published" >> "$GITHUB_STEP_SUMMARY"
|
||||
else
|
||||
echo "### Published $NODE_ID $VERSION" >> "$GITHUB_STEP_SUMMARY"
|
||||
fi
|
||||
@@ -0,0 +1,114 @@
|
||||
name: Publish to Comfy registry
|
||||
on:
|
||||
workflow_dispatch:
|
||||
push:
|
||||
branches:
|
||||
- main
|
||||
paths:
|
||||
- "pyproject.toml"
|
||||
- ".github/workflows/publish.yml"
|
||||
|
||||
concurrency:
|
||||
group: comfy-registry-${{ github.repository }}
|
||||
cancel-in-progress: false
|
||||
|
||||
env:
|
||||
COMFY_CLI_VERSION: "1.13.0"
|
||||
|
||||
jobs:
|
||||
publish-node:
|
||||
name: Publish Custom Node to registry
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
permissions:
|
||||
contents: read
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@v7
|
||||
with:
|
||||
python-version: "3.12"
|
||||
- name: Read release metadata
|
||||
id: metadata
|
||||
run: |
|
||||
python - <<'PY'
|
||||
import os
|
||||
import tomllib
|
||||
from pathlib import Path
|
||||
|
||||
metadata = tomllib.loads(Path("pyproject.toml").read_text(encoding="utf-8"))
|
||||
node_id = metadata["project"]["name"]
|
||||
version = metadata["project"]["version"]
|
||||
publisher = metadata["tool"]["comfy"]["PublisherId"]
|
||||
if publisher != "gokayfem":
|
||||
raise SystemExit(f"Expected publisher 'gokayfem', found {publisher!r}")
|
||||
|
||||
with Path(os.environ["GITHUB_OUTPUT"]).open("a", encoding="utf-8") as output:
|
||||
print(f"node_id={node_id}", file=output)
|
||||
print(f"version={version}", file=output)
|
||||
PY
|
||||
- name: Check Registry version
|
||||
id: registry
|
||||
env:
|
||||
NODE_ID: ${{ steps.metadata.outputs.node_id }}
|
||||
VERSION: ${{ steps.metadata.outputs.version }}
|
||||
run: |
|
||||
python - <<'PY'
|
||||
import json
|
||||
import os
|
||||
import urllib.parse
|
||||
import urllib.request
|
||||
from pathlib import Path
|
||||
|
||||
node_id = urllib.parse.quote(os.environ["NODE_ID"], safe="")
|
||||
request = urllib.request.Request(
|
||||
f"https://api.comfy.org/nodes/{node_id}/versions",
|
||||
headers={"Accept": "application/json", "User-Agent": "comfy-node-publisher"},
|
||||
)
|
||||
with urllib.request.urlopen(request, timeout=30) as response:
|
||||
versions = json.load(response)
|
||||
|
||||
exists = any(item.get("version") == os.environ["VERSION"] for item in versions)
|
||||
with Path(os.environ["GITHUB_OUTPUT"]).open("a", encoding="utf-8") as output:
|
||||
print(f"exists={'true' if exists else 'false'}", file=output)
|
||||
PY
|
||||
- name: Check publisher credential
|
||||
if: steps.registry.outputs.exists != 'true'
|
||||
id: credentials
|
||||
env:
|
||||
REGISTRY_ACCESS_TOKEN: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
run: |
|
||||
if [[ -n "$REGISTRY_ACCESS_TOKEN" ]]; then
|
||||
echo "available=true" >> "$GITHUB_OUTPUT"
|
||||
else
|
||||
echo "available=false" >> "$GITHUB_OUTPUT"
|
||||
echo "::notice title=Central publisher enabled::The secure fleet publisher will publish this release within one hour."
|
||||
fi
|
||||
- name: Install pinned Comfy CLI
|
||||
if: steps.registry.outputs.exists != 'true' && steps.credentials.outputs.available == 'true'
|
||||
shell: bash
|
||||
run: python -m pip install --disable-pip-version-check "comfy-cli==${COMFY_CLI_VERSION}"
|
||||
- name: Publish Custom Node
|
||||
if: steps.registry.outputs.exists != 'true' && steps.credentials.outputs.available == 'true'
|
||||
id: publish
|
||||
continue-on-error: true
|
||||
shell: bash
|
||||
env:
|
||||
REGISTRY_ACCESS_TOKEN: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
|
||||
run: comfy --skip-prompt --no-enable-telemetry node publish --token "$REGISTRY_ACCESS_TOKEN"
|
||||
- name: Record publication result
|
||||
env:
|
||||
NODE_ID: ${{ steps.metadata.outputs.node_id }}
|
||||
VERSION: ${{ steps.metadata.outputs.version }}
|
||||
ALREADY_PUBLISHED: ${{ steps.registry.outputs.exists }}
|
||||
PUBLISH_OUTCOME: ${{ steps.publish.outcome }}
|
||||
run: |
|
||||
if [[ "$ALREADY_PUBLISHED" == "true" ]]; then
|
||||
echo "### $NODE_ID $VERSION already published" >> "$GITHUB_STEP_SUMMARY"
|
||||
elif [[ "$PUBLISH_OUTCOME" == "success" ]]; then
|
||||
echo "### Published $NODE_ID $VERSION" >> "$GITHUB_STEP_SUMMARY"
|
||||
else
|
||||
echo "::notice title=Central publishing handoff::The secure fleet publisher will retry this release within one hour."
|
||||
echo "### $NODE_ID $VERSION queued for the fleet publisher" >> "$GITHUB_STEP_SUMMARY"
|
||||
fi
|
||||
@@ -152,6 +152,13 @@ dmypy.json
|
||||
# Cython debug symbols
|
||||
cython_debug/
|
||||
|
||||
# Sites needs this small source plugin; it is not a generated build output.
|
||||
!benchmarks/site/build/
|
||||
!benchmarks/site/build/sites-vite-plugin.ts
|
||||
|
||||
# Rebuildable TensorRT engine archives are too large for Git.
|
||||
benchmarks/results/*.ep
|
||||
|
||||
# PyCharm
|
||||
# JetBrains specific template is maintained in a separate JetBrains.gitignore that can
|
||||
# be found at https://github.com/github/gitignore/blob/main/Global/JetBrains.gitignore
|
||||
|
||||
+199
@@ -0,0 +1,199 @@
|
||||
# Changelog
|
||||
|
||||
All notable changes to this project are documented here.
|
||||
|
||||
The format follows [Keep a Changelog](https://keepachangelog.com/en/1.1.0/),
|
||||
and this project adheres to [Semantic Versioning](https://semver.org/spec/v2.0.0.html).
|
||||
|
||||
Versions are published to the [Comfy Registry](https://registry.comfy.org/)
|
||||
from `pyproject.toml`. A release is only published when `version` changes, so
|
||||
every user-visible fix needs a version bump.
|
||||
|
||||
## [3.5.0] - 2026-07-31
|
||||
|
||||
### Added
|
||||
|
||||
- A MiniMax music node with fixed global and China endpoints, generation and
|
||||
cover model selection, regional request fields, URL and hexadecimal response
|
||||
decoding, and MP3, WAV, and PCM output through the existing audio contract.
|
||||
|
||||
### Security
|
||||
|
||||
- MiniMax credentials are read only from `MINIMAX_API_KEY`; workflows cannot
|
||||
supply a key or redirect it to a custom endpoint, and request errors redact
|
||||
the resolved value before reaching ComfyUI.
|
||||
|
||||
## [3.4.0] - 2026-07-31
|
||||
|
||||
### Added
|
||||
|
||||
- A robotics-safe VLA layer with typed embodiment, observation, and action
|
||||
contracts; bounded multi-camera history; trajectory inspection and preview;
|
||||
action-chunk replanning; and explicit bounds, rate, dimension, horizon, and
|
||||
non-finite-value checks before handoff.
|
||||
- Native policy clients for OpenPI's WebSocket protocol and NVIDIA Isaac
|
||||
GR00T's ZeroMQ protocol, plus a portable authenticated HTTP/JPEG protocol for
|
||||
isolated policy runtimes.
|
||||
- An isolated current-LeRobot policy server with pre/postprocessor support,
|
||||
serialized inference, optional idle CPU offload, checkpoint feature metadata,
|
||||
and environment-only bearer authentication.
|
||||
- A curated 15-model VLA catalog covering SmolVLA, X-VLA, the OpenPI family,
|
||||
GR00T N1.7, WALL-OSS, MolmoAct2, VLA-JEPA, LingBot-VA, FastWAM, EO-1, EVO-1,
|
||||
OpenVLA-OFT, and Octo with explicit readiness and fine-tuning requirements.
|
||||
- A complete API workflow, setup guide, compatibility matrix, security
|
||||
guidance, and real-weight SmolVLA validation on an RTX 3090.
|
||||
|
||||
### Security
|
||||
|
||||
- Workflow JSON never stores robotics API keys. The clients read only
|
||||
`VLA_POLICY_TOKEN`, `OPENPI_API_KEY`, or `GROOT_API_TOKEN` from the
|
||||
environment, redact them from errors/reports, reject embedded URL
|
||||
credentials, and require encrypted transports plus explicit opt-in for
|
||||
remote endpoints where the upstream protocol supports encryption.
|
||||
- The included policy server bounds request, camera, history, and response
|
||||
sizes and never uses pickle across the network.
|
||||
|
||||
## [3.3.1] - 2026-07-30
|
||||
|
||||
### Fixed
|
||||
|
||||
- Package metadata declared `license = "MIT"` while the bundled `LICENSE` has
|
||||
been Apache-2.0 since the initial commit. Built wheels therefore contained
|
||||
contradictory MIT metadata and Apache-2.0 license text. The Registry already
|
||||
referenced the license file and was unaffected. Metadata now says
|
||||
`Apache-2.0`.
|
||||
- Moondream 2 and Moondream 3.1 local inference (`b8ae298`).
|
||||
- SmolVLM setup dependencies (`c13ee23`).
|
||||
|
||||
The two fixes above landed on `main` after 3.3.0 without a version bump, so
|
||||
the Registry publish workflow saw 3.3.0 already published and skipped them.
|
||||
They reach Registry users for the first time in 3.3.1.
|
||||
|
||||
### Added
|
||||
|
||||
- Test coverage for the GGUF text and multimodal node families, which
|
||||
previously had none: `nodes/suggest.py` (0% to 98%) and
|
||||
`nodes/llavaloader.py` (0% to 99%). The new cases pin the behaviours behind
|
||||
the pack's longest-running bug reports: widget ordering (#156), sampling
|
||||
kwarg plumbing (#144), and handle teardown on both success and failure
|
||||
(#137).
|
||||
- `ruff` lint gate and a coverage floor in CI, plus `requirements-dev.txt`
|
||||
for the tooling.
|
||||
- `CHANGELOG.md`, `CONTRIBUTING.md`, issue and pull request templates, and a
|
||||
Dependabot configuration.
|
||||
- A complete node reference in the README covering all 78 registered nodes.
|
||||
|
||||
## [3.3.0] - 2026-07-29
|
||||
|
||||
### Added
|
||||
|
||||
- Moondream Photon support and universal VLM acceleration utilities, including
|
||||
the image pixel-budget and performance-profile nodes (`102f166`).
|
||||
|
||||
## [3.2.0] - 2026-07-29
|
||||
|
||||
### Added
|
||||
|
||||
- Adaptive video intelligence with temporal reasoning, plus the text workflow
|
||||
toolkit (join, template, clean, replace, split, JSON extract, inspect)
|
||||
(`44fefcb`).
|
||||
|
||||
## [3.1.0] - 2026-07-29
|
||||
|
||||
### Changed
|
||||
|
||||
- Hosted LLM and VLM API nodes modernized and hardened, with provider profiles
|
||||
for OpenAI, Google Gemini, Anthropic, xAI, DeepSeek, and others (`505b324`).
|
||||
|
||||
## [3.0.0] - 2026-07-29
|
||||
|
||||
### Added
|
||||
|
||||
- Unified vision stack: open-vocabulary detection (Grounding DINO, OWLv2,
|
||||
OmDet), SAM2.1 and SAM3.1 segmentation, tracking, and creator mask tools,
|
||||
with structured detection/segmentation schemas (`39fc116`).
|
||||
|
||||
### Changed
|
||||
|
||||
- **Breaking:** detection and segmentation nodes now emit structured data
|
||||
types rather than loose strings. Workflows wiring these outputs into text
|
||||
nodes need the new converter utilities.
|
||||
|
||||
## [2.3.0] - 2026-07-29
|
||||
|
||||
### Added
|
||||
|
||||
- Reliable streaming VLM text output (`239c904`).
|
||||
|
||||
## [2.2.0] - 2026-07-29
|
||||
|
||||
### Changed
|
||||
|
||||
- llama.cpp GGUF runtime modernized. `llama-cpp-agent` was removed in favour
|
||||
of llama-cpp-python's native JSON Schema support, which resolves the
|
||||
unstable wrapper API behind the `unexpected keyword argument 'temperature'`
|
||||
crashes (#144).
|
||||
|
||||
## [2.1.0] - 2026-07-28
|
||||
|
||||
### Added
|
||||
|
||||
- Cross-platform runtime support across NVIDIA CUDA, AMD ROCm, Apple Metal,
|
||||
Intel XPU, and CPU, without replacing ComfyUI's PyTorch (`4c200c4`).
|
||||
|
||||
## [2.0.1] - 2026-07-28
|
||||
|
||||
### Added
|
||||
|
||||
- Small VLM catalog and real-weight model validation evidence
|
||||
(see `MODEL_VALIDATION.md`) (`460b27a`).
|
||||
|
||||
## [2.0.0] - 2026-07-28
|
||||
|
||||
### Changed
|
||||
|
||||
- **Breaking:** node pack modernized with an explicit GPU lifecycle. Models
|
||||
now load lazily on first execution and register with ComfyUI's model manager
|
||||
so they participate in smart VRAM offloading, which addresses models
|
||||
remaining resident after generation (#137) (`b89f628`).
|
||||
- **Breaking:** `forceInput` string hacks removed from node schemas. They
|
||||
corrupted the widget index during serialization and shifted inputs on saved
|
||||
workflows (#156). Use the native right-click "Convert to Input" instead.
|
||||
- Import is now failure-isolated: a broken optional model cannot prevent
|
||||
unrelated nodes from loading (#94, #145).
|
||||
- `numpy` is no longer pinned. The old `numpy<2.0.0` pin crashed startup on
|
||||
NumPy 2.x environments (#157).
|
||||
- Model coverage moved to current releases, including Qwen 3 / 3.5 VL,
|
||||
SmolVLM2, InternVL, Granite Vision, and Gemma 3 (#148, #151). The
|
||||
unmaintained InternLM-XComposer2 nodes were dropped (#139).
|
||||
|
||||
### Removed
|
||||
|
||||
- **Breaking:** `llama-cpp-agent` dependency (see 2.2.0).
|
||||
- **Breaking:** InternLM-XComposer2 nodes, which depended on an AutoGPTQ stack
|
||||
that pinned incompatible PyTorch versions (#139).
|
||||
|
||||
## 1.0.0 - 1.0.6 (2024-05-20 to 2024-11-03)
|
||||
|
||||
Initial packaged releases, predating changelog tracking. This line covered
|
||||
LLaVA GGUF loaders and samplers, Moondream, Kosmos-2, JoyTag, UForm,
|
||||
MiniCPM-V, PaLI-Gemma, Florence-2, Molmo, Qwen2-VL, the LLM prompt and
|
||||
suggestion generators, AudioLDM2, and ChatMusician. See the
|
||||
[commit history](https://github.com/gokayfem/ComfyUI_VLM_nodes/commits/main)
|
||||
for detail.
|
||||
|
||||
Tagging began at 3.3.0. Earlier versions link to the commit that declared
|
||||
them, because retroactively tagging them would run current CI against code
|
||||
that predates it.
|
||||
|
||||
[3.4.0]: https://github.com/gokayfem/ComfyUI_VLM_nodes/compare/v3.3.1...v3.4.0
|
||||
[3.3.1]: https://github.com/gokayfem/ComfyUI_VLM_nodes/compare/v3.3.0...v3.3.1
|
||||
[3.3.0]: https://github.com/gokayfem/ComfyUI_VLM_nodes/releases/tag/v3.3.0
|
||||
[3.2.0]: https://github.com/gokayfem/ComfyUI_VLM_nodes/commit/44fefcb
|
||||
[3.1.0]: https://github.com/gokayfem/ComfyUI_VLM_nodes/commit/505b324
|
||||
[3.0.0]: https://github.com/gokayfem/ComfyUI_VLM_nodes/commit/39fc116
|
||||
[2.3.0]: https://github.com/gokayfem/ComfyUI_VLM_nodes/commit/239c904
|
||||
[2.2.0]: https://github.com/gokayfem/ComfyUI_VLM_nodes/commit/0da5070
|
||||
[2.1.0]: https://github.com/gokayfem/ComfyUI_VLM_nodes/commit/4c200c4
|
||||
[2.0.1]: https://github.com/gokayfem/ComfyUI_VLM_nodes/commit/460b27a
|
||||
[2.0.0]: https://github.com/gokayfem/ComfyUI_VLM_nodes/commit/b89f628
|
||||
@@ -0,0 +1,21 @@
|
||||
cff-version: 1.2.0
|
||||
message: "If you use ComfyUI VLM Nodes in your work, please cite it using the metadata below."
|
||||
type: software
|
||||
title: "ComfyUI VLM Nodes"
|
||||
version: "3.5.0"
|
||||
date-released: 2026-07-31
|
||||
authors:
|
||||
- family-names: "Aydoğan"
|
||||
given-names: "Gökay"
|
||||
orcid: "https://orcid.org/0000-0002-2343-9433"
|
||||
abstract: "Production-ready local and API vision-language, structured prompting, audio, and utility nodes for ComfyUI."
|
||||
keywords:
|
||||
- ComfyUI
|
||||
- vision-language models
|
||||
- multimodal AI
|
||||
- image understanding
|
||||
- video understanding
|
||||
- generative AI
|
||||
license: Apache-2.0
|
||||
repository-code: "https://github.com/gokayfem/ComfyUI_VLM_nodes"
|
||||
url: "https://github.com/gokayfem/ComfyUI_VLM_nodes"
|
||||
@@ -0,0 +1,293 @@
|
||||
# Platform and accelerator compatibility
|
||||
|
||||
ComfyUI owns PyTorch. This node pack deliberately does not depend on `torch`,
|
||||
`torchvision`, or a vendor wheel, because installing a generic PyPI build can
|
||||
silently replace a working CUDA, ROCm, XPU, or Metal environment.
|
||||
|
||||
Install `requirements.txt` with the same Python executable that starts ComfyUI.
|
||||
The **VLM Runtime Diagnostics** node reports the environment seen by the pack
|
||||
without downloading a model.
|
||||
|
||||
## Support matrix
|
||||
|
||||
| Platform | Managed Transformers | bitsandbytes 4/8-bit | GGUF acceleration |
|
||||
| --- | --- | --- | --- |
|
||||
| Linux + NVIDIA | CUDA, BF16/FP16 capability detected | Official wheel | CUDA or Vulkan |
|
||||
| Windows + NVIDIA | CUDA, BF16/FP16 capability detected | Official wheel | CUDA or Vulkan |
|
||||
| Linux + AMD | ROCm through PyTorch's `cuda` API | Official ROCm wheel for listed GPU architectures | ROCm/HIP or Vulkan |
|
||||
| Windows + AMD | Current ComfyUI/AMD ROCm PyTorch builds | Official ROCm Windows wheel for listed GPU architectures | HIP Radeon or Vulkan |
|
||||
| Apple Silicon macOS | MPS, BF16 on supported macOS/PyTorch; FP16 fallback | Official arm64 wheel | Metal |
|
||||
| Intel GPU | XPU with BF16 capability detection | Official XPU/CPU wheel | SYCL or Vulkan |
|
||||
| CPU | FP32 | Official wheels on supported architectures | OpenBLAS or default CPU |
|
||||
| Intel macOS | CPU/legacy MPS environment as provided by ComfyUI | No official bitsandbytes wheel; dependency is skipped | CPU build |
|
||||
|
||||
The default **ComfyUI managed** mode is the portable path. Quantization is an
|
||||
optional optimization, not an import requirement. DirectML/private-use devices
|
||||
receive a safe FP32 fallback, but are best-effort because current ComfyUI itself
|
||||
does not treat DirectML as a primary performance backend.
|
||||
|
||||
## Detection and segmentation backends
|
||||
|
||||
The structured vision nodes do not install a second PyTorch build. Grounding
|
||||
DINO, OWLv2, OmDet Turbo, Florence-2, and SAM2.1 use the device selected by
|
||||
ComfyUI and participate in its model loading/offloading lifecycle. The core
|
||||
SAM3.1 adapter performs schema validation and report generation on the compact
|
||||
core payload; ComfyUI itself owns SAM3 inference and mask packing.
|
||||
|
||||
| Backend | Detection / Florence | SAM2.1 video | Comfy core SAM3.1 | Practical limitation |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| NVIDIA CUDA | Managed BF16 when supported, otherwise FP16 | Preferred accelerated path; CPU state/storage is the default | Supported when the installed ComfyUI version recognizes the checkpoint | Resolution, frame count, and object count still dominate VRAM/RAM |
|
||||
| AMD ROCm on Linux | Uses PyTorch's `cuda` device and BF16/FP16 capability checks | Same managed path; keep inference state on CPU unless measured otherwise | Follows ComfyUI core ROCm support | Individual Transformers kernels may fall back or differ in performance |
|
||||
| AMD ROCm on Windows | Uses the device exposed by the selected ComfyUI PyTorch build | Same API contract | Follows that ComfyUI build | Treat as hardware-validation pending, not equivalent to a Linux ROCm pass |
|
||||
| Apple Metal / MPS | FP16, or BF16 only when macOS/PyTorch report support | Supported contract with CPU video storage; use Tiny and short slices first | Follows ComfyUI core MPS support | Unified memory is shared with the OS; unsupported operators may fall back to CPU |
|
||||
| Intel XPU | BF16/FP16 capability-selected managed path | Supported contract; use CPU state for portability | Follows ComfyUI core XPU support | Model-specific operator coverage and real throughput require hardware validation |
|
||||
| CPU | FP32 portable path | Functionally supported but slow; use Tiny, low resolution, and short slices | Adapter/report works; core SAM3 inference is memory intensive | No half-precision speed assumption and no accelerator kernel |
|
||||
|
||||
`precision=auto` is the safe default for open-vocabulary detection and SAM2.1.
|
||||
Explicit BF16 silently falls back to FP16 or FP32 when the selected backend
|
||||
cannot execute BF16. This is a portability fallback, not proof that every
|
||||
model family has been run on every vendor device. See
|
||||
[MODEL_VALIDATION.md](MODEL_VALIDATION.md) for real-hardware evidence.
|
||||
|
||||
### Moondream 3 / 3.1 Photon
|
||||
|
||||
Moondream Photon is deliberately isolated from ComfyUI's main Python environment
|
||||
because `moondream==1.3.0` requires Pillow 10 while current ComfyUI uses a
|
||||
newer Pillow. Its worker cache, virtual environment, and logs live under
|
||||
`models/LLavacheckpoints/moondream31-runtime`; it never replaces ComfyUI's
|
||||
PyTorch or Pillow.
|
||||
|
||||
| Platform | Official local Photon support | This integration |
|
||||
| --- | --- | --- |
|
||||
| Linux/WSL + NVIDIA Ampere or newer | Supported | 3.1 query/caption/detection/pointing; 3 Preview SVG segmentation |
|
||||
| Windows + NVIDIA Ampere or newer | Supported | Same isolated worker contract |
|
||||
| Apple Silicon macOS 13+ | Supported with MPS | Same contract; use a conservative KV-cache profile on low-memory systems |
|
||||
| AMD ROCm, Intel GPU, CPU | Not currently provided upstream | Node stays importable and fails before model work with an actionable support message |
|
||||
|
||||
The final Moondream 3.1 model card lists query, caption, detect, and point; it
|
||||
does not list segment. Native SVG segment uses `moondream3-preview`, and the
|
||||
loader rejects a 3.1/segment mismatch before inference.
|
||||
|
||||
`max_batch_size` controls Photon's scheduler capacity. The detection, point,
|
||||
and preview-segmentation nodes issue `parallel_requests` frame requests concurrently,
|
||||
allowing Photon to build GPU batches. `frame_stride` bounds work for high-frame
|
||||
rate sources. Performance JSON records warm worker time, end-to-end time,
|
||||
processed/skipped frames, worker/sustained FPS, target sampled FPS, and
|
||||
real-time factor; it is a measurement from the current run, not a universal
|
||||
benchmark claim.
|
||||
|
||||
### Video memory and chunking
|
||||
|
||||
- Core `Video Slice` should bound work before `GetVideoComponents` materializes
|
||||
frames. Scale the resulting `IMAGE` batch before running detection or
|
||||
segmentation.
|
||||
- Open-vocabulary detection runs frame by frame. SAM2.1 keeps source frames on
|
||||
CPU, defaults its inference state to CPU, and caches at most one vision
|
||||
feature in the video session.
|
||||
- SAM2.1 output masks and previews are CPU tensors. Core SAM3 keeps its track
|
||||
masks bit-packed; `VLMSAM3TrackAdapter` does not unpack the complete volume.
|
||||
- `unload_after=true` releases the node's owned detector/SAM2 model after a
|
||||
run. Leave it false for repeated work with one model; set it true before a
|
||||
different large family must load on a constrained accelerator.
|
||||
- Each slice or queue run starts a new propagation/tracking session. Carrying
|
||||
an ID across independent chunks requires an explicit application-level
|
||||
overlap/reconciliation step; the nodes never claim cross-run identity.
|
||||
|
||||
### Model licenses and access
|
||||
|
||||
Model licenses are independent from this repository's code license. Check the
|
||||
model card before redistributing weights or outputs.
|
||||
|
||||
- The `facebook/sam2.1-hiera-*` Transformers checkpoints are published under
|
||||
Apache-2.0.
|
||||
- Meta SAM3 uses the SAM License. The upstream `facebook/sam3` repository is
|
||||
access-gated and asks the Hugging Face account holder to accept its terms and
|
||||
share the requested contact information.
|
||||
- ComfyUI's `Comfy-Org/sam3.1` checkpoint is marked `sam-license`; the example
|
||||
expects `sam3.1_multiplex_fp16.safetensors` under
|
||||
`ComfyUI/models/checkpoints`.
|
||||
- `HF_TOKEN` is used when Hugging Face requires authenticated access. Tokens
|
||||
must be supplied by the environment and must not be embedded in workflows.
|
||||
- Moondream 3.1 uses the Moondream Model License 1.0. The Loader requires an
|
||||
explicit workflow acknowledgement. The license permits local product use
|
||||
but restricts offering general-purpose hosted Moondream access; review the
|
||||
current upstream terms for the intended deployment.
|
||||
|
||||
Authoritative references:
|
||||
|
||||
- [Meta SAM3 model and access terms](https://huggingface.co/facebook/sam3)
|
||||
- [Meta SAM3 license](https://huggingface.co/facebook/sam3/blob/main/LICENSE)
|
||||
- [ComfyUI SAM3.1 checkpoint](https://huggingface.co/Comfy-Org/sam3.1)
|
||||
- [SAM2.1 Hiera Tiny model card](https://huggingface.co/facebook/sam2.1-hiera-tiny)
|
||||
- [Moondream 3.1 model card](https://huggingface.co/moondream/moondream3.1-9B-A2B)
|
||||
- [Moondream Model License 1.0](https://moondream.ai/licenses/model/1.0)
|
||||
|
||||
## Dependency behavior
|
||||
|
||||
- Python 3.10 through 3.13 is covered by CI.
|
||||
- `transformers>=5.4,<6` and `huggingface-hub>=1.5,<2` are paired intentionally;
|
||||
Transformers 5.4 requires Hub 1.5 or newer.
|
||||
- `bitsandbytes>=0.50` is the first dependency floor used here for the current
|
||||
multi-backend releases. Environment markers prevent an unsupported wheel
|
||||
from blocking the whole node pack.
|
||||
- `requirements-quantization.txt` is available for an explicit quantization
|
||||
install or source-build environment.
|
||||
- `requirements-moondream31.txt` belongs only in the isolated Photon sidecar;
|
||||
installing it into ComfyUI's environment would create a Pillow conflict.
|
||||
- Model downloads, imports, and package compilation never occur during node
|
||||
discovery.
|
||||
|
||||
## Robotics / VLA policy compatibility
|
||||
|
||||
ComfyUI's robotics schemas, safety gate, trajectory tools, and universal HTTP
|
||||
client run wherever this node pack runs. Policy runtime compatibility is
|
||||
separate:
|
||||
|
||||
| Policy route | ComfyUI client | Policy environment | Practical boundary |
|
||||
| --- | --- | --- | --- |
|
||||
| Universal VLA HTTP | Windows, Linux, macOS; CUDA, ROCm, Metal, XPU, CPU | Any host that implements `comfyui-vla-http-v1` | Loopback HTTP or trusted HTTPS; no pickle |
|
||||
| LeRobot sidecar | Same universal client | Current LeRobot supports Linux, Windows, and macOS; individual policy extras/operators vary | Python/PyTorch live outside ComfyUI; fine-tuned checkpoint required for the target embodiment |
|
||||
| openpi WebSocket | Lightweight optional client on every ComfyUI platform | Upstream currently tests Ubuntu 22.04 + NVIDIA, inference above 8 GB VRAM | Use WSL/Docker/Linux server; remote transport must be WSS |
|
||||
| Isaac-GR00T N1.7 ZMQ | Lightweight optional client on every ComfyUI platform | NVIDIA CUDA/Jetson Linux according to upstream deployment matrix | ZMQ has no transport encryption; use a private network/tunnel |
|
||||
| OpenVLA-OFT | Universal client with a project-specific bridge | Upstream PyTorch/CUDA environment | OFT is the preferred high-frequency multi-image OpenVLA route |
|
||||
| Octo | Universal client with a project-specific bridge | Isolated JAX environment | Kept as a lightweight research baseline, not the default maintained runtime |
|
||||
|
||||
Install only the native client protocols into ComfyUI:
|
||||
|
||||
```bash
|
||||
python -m pip install -r requirements-robotics-client.txt
|
||||
```
|
||||
|
||||
Do not install `lerobot[all]`, openpi, Isaac-GR00T, OpenVLA, or JAX into
|
||||
ComfyUI's Python. The included LeRobot HTTP sidecar belongs in its own
|
||||
environment and optionally moves its owned policy to CPU after an idle
|
||||
interval. It does not flush ComfyUI's accelerator cache.
|
||||
|
||||
An embodiment profile is a workflow contract, not a hardware certification.
|
||||
The supplied profiles are visibly labeled templates. Before real deployment,
|
||||
replace action bounds/deltas with the trained dataset's semantics and the
|
||||
manufacturer/controller limits. ComfyUI never opens ROS, serial, CAN, or robot
|
||||
SDK transports.
|
||||
|
||||
Install manually:
|
||||
|
||||
```bash
|
||||
python -m pip install -r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements.txt
|
||||
```
|
||||
|
||||
If quantization was skipped but the machine has a supported custom build:
|
||||
|
||||
```bash
|
||||
python -m pip install -r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements-quantization.txt
|
||||
```
|
||||
|
||||
## llama.cpp / GGUF
|
||||
|
||||
`llama-cpp-python` must be compiled or selected for the actual backend. Its
|
||||
official project currently publishes backend indexes and documents source
|
||||
build flags:
|
||||
|
||||
```bash
|
||||
# NVIDIA; choose a wheel supported by the installed driver.
|
||||
python -m pip install llama-cpp-python \
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/cu124
|
||||
|
||||
# Apple Metal
|
||||
python -m pip install llama-cpp-python \
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/metal
|
||||
|
||||
# Linux ROCm
|
||||
python -m pip install llama-cpp-python \
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/rocm72
|
||||
|
||||
# Linux or Windows Vulkan
|
||||
python -m pip install llama-cpp-python \
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/vulkan
|
||||
```
|
||||
|
||||
If an Apple Metal wheel is unavailable or fails archive validation, build the
|
||||
same optional requirement from source:
|
||||
|
||||
```bash
|
||||
CMAKE_ARGS="-DGGML_METAL=on" python -m pip install \
|
||||
--no-cache-dir --no-binary llama-cpp-python \
|
||||
-r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements-llama-cpp.txt
|
||||
```
|
||||
|
||||
The official Windows HIP Radeon index is:
|
||||
|
||||
```powershell
|
||||
python -m pip install llama-cpp-python `
|
||||
--extra-index-url https://abetlen.github.io/llama-cpp-python/whl/hip-radeon
|
||||
```
|
||||
|
||||
Source builds use `GGML_CUDA=on`, `GGML_METAL=on`, `GGML_HIP=on`,
|
||||
`GGML_VULKAN=on`, or `GGML_SYCL=on` through `CMAKE_ARGS`. Use an arm64 Python
|
||||
on Apple Silicon; an x86 Python builds the wrong architecture and is
|
||||
dramatically slower.
|
||||
|
||||
The llama.cpp wheel is an independent native runtime; it does not have to use
|
||||
the same accelerator API as ComfyUI's PyTorch wheel. For example, a Vulkan
|
||||
llama.cpp wheel can coexist with a CUDA or CPU PyTorch build. The nodes query
|
||||
`llama_supports_gpu_offload`, `llama_supports_mmap`, and llama.cpp's system
|
||||
information at runtime. They never label a wheel CUDA/ROCm/Metal based only on
|
||||
`torch`.
|
||||
|
||||
### GGUF runtime controls
|
||||
|
||||
- `gpu_layers=-1` requests full accelerator offload. A build that reports no
|
||||
offload support is automatically clamped to `0` and continues on CPU.
|
||||
- `n_batch` is the logical prompt batch and `n_ubatch` is the physical
|
||||
micro-batch. The runtime clamps both to the selected context and guarantees
|
||||
`n_ubatch <= n_batch`.
|
||||
- **Auto** flash attention enables the optimized path for accelerator offload
|
||||
and retries once without it only when llama.cpp reports an attention-related
|
||||
initialization failure. **Enabled** remains strict; **Disabled** is the
|
||||
maximum-compatibility setting.
|
||||
- `use_mmap` is honored only when the compiled backend reports mmap support.
|
||||
- Layer, row, and single-device split modes plus `main_gpu` and
|
||||
comma-separated `tensor_split` weights are passed through when supported by
|
||||
the installed binding. Parallel multi-GPU is primarily a CUDA/ROCm feature;
|
||||
Vulkan and SYCL support is more limited.
|
||||
- Current multimodal GGUFs should use **Auto (GGUF chat template)**, which maps
|
||||
to llama.cpp's MTMD handler. Named legacy handlers remain selectable for
|
||||
model cards that require an exact prompt format.
|
||||
- Every model handle is lazy, mutex-protected, cache-keyed by all performance
|
||||
settings, and closes its exact model and projector handler on unload.
|
||||
|
||||
Authoritative installation references:
|
||||
|
||||
- [ComfyUI installation and hardware backends](https://github.com/Comfy-Org/ComfyUI)
|
||||
- [bitsandbytes installation and supported hardware](https://huggingface.co/docs/bitsandbytes/installation)
|
||||
- [llama-cpp-python supported backends](https://github.com/abetlen/llama-cpp-python#supported-backends)
|
||||
- [llama-cpp-python API reference](https://llama-cpp-python.readthedocs.io/en/latest/api-reference/)
|
||||
- [llama.cpp backend feature matrix](https://github.com/ggml-org/llama.cpp/wiki/Feature-matrix)
|
||||
|
||||
## Attention and offloading
|
||||
|
||||
- **Auto (SDPA)** lets PyTorch choose its maintained kernel and is the default
|
||||
on every backend.
|
||||
- **Flash Attention 2** is preflighted for CUDA/ROCm only. A compatible
|
||||
`flash-attn` build is still required.
|
||||
- ComfyUI-managed models participate in its normal model patcher lifecycle.
|
||||
- External bitsandbytes and llama.cpp allocations ask ComfyUI to free space
|
||||
first, then release only their owned model on unload.
|
||||
- Automatic CPU/disk device mapping is used for large CUDA/ROCm/XPU models.
|
||||
MPS unified memory and CPU use an explicit active-device map.
|
||||
- AudioLDM2 uses FP16 on capable accelerators, FP32 on CPU, CUDA-API CPU
|
||||
offload for NVIDIA/ROCm, and a portable CPU random generator on MPS.
|
||||
|
||||
## What CI proves
|
||||
|
||||
Every push installs current ComfyUI plus this complete `requirements.txt` and
|
||||
runs imports, schemas, runtime contracts, tests, and byte-compilation on:
|
||||
|
||||
- Ubuntu, Python 3.10
|
||||
- Ubuntu, Python 3.13
|
||||
- Windows, Python 3.12
|
||||
- macOS, Python 3.12
|
||||
|
||||
Hosted runners do not contain production NVIDIA, AMD, or Intel GPUs. CI
|
||||
therefore tests backend selection and dtype/device-map contracts, while real
|
||||
GPU model smoke tests remain explicit hardware validation. It does not claim
|
||||
that a CPU simulation executed a vendor kernel.
|
||||
+106
@@ -0,0 +1,106 @@
|
||||
# Contributing
|
||||
|
||||
Thanks for helping out. This pack runs inside other people's ComfyUI installs
|
||||
on five accelerator backends, so a few rules exist to keep it from breaking
|
||||
them.
|
||||
|
||||
## The rules that matter most
|
||||
|
||||
**Importing the pack must never download a model, install a package, compile
|
||||
anything, or allocate VRAM.** Models load on first execution. This is enforced
|
||||
by `tests/test_nodes.py`, which asserts the source contains no `pip install`,
|
||||
no `subprocess.run`, and no direct `torch.cuda.empty_cache`.
|
||||
|
||||
**Never reorder or insert widgets in an existing node's `INPUT_TYPES`.** Comfy
|
||||
serializes widget values by position, so a reordered schema silently rebinds
|
||||
every saved workflow. Add new inputs to `optional` at the end. The widget order
|
||||
of the long-lived nodes is pinned by tests; if a test fails because you moved a
|
||||
widget, the test is right.
|
||||
|
||||
**Never use `forceInput`.** It corrupts the widget index during serialization.
|
||||
Users get the same result from the native right-click "Convert to Input".
|
||||
|
||||
**An optional dependency must fail only the node that needs it.** Use
|
||||
`require_module()` from `nodes/runtime.py`, which raises an actionable error at
|
||||
execution time rather than at import time.
|
||||
|
||||
**Do not install or replace `torch`.** ComfyUI's own installer picks the CUDA,
|
||||
ROCm, XPU, Metal, or CPU build. The same applies to `numpy` and `Pillow`.
|
||||
|
||||
## Setting up
|
||||
|
||||
```bash
|
||||
cd ComfyUI/custom_nodes
|
||||
git clone https://github.com/gokayfem/ComfyUI_VLM_nodes.git
|
||||
cd ComfyUI_VLM_nodes
|
||||
python -m pip install -r requirements.txt -r requirements-dev.txt
|
||||
```
|
||||
|
||||
Use ComfyUI's Python. On ComfyUI Portable there is no `activate` script, so
|
||||
call the interpreter directly:
|
||||
|
||||
```
|
||||
..\..\python_embeded\python.exe -m pip install -r requirements.txt
|
||||
```
|
||||
|
||||
## Running checks
|
||||
|
||||
```bash
|
||||
PYTHONPATH=/path/to/custom_nodes:/path/to/ComfyUI python -m pytest -q
|
||||
python -m ruff check .
|
||||
```
|
||||
|
||||
`PYTHONPATH` needs the directory *containing* this checkout plus ComfyUI
|
||||
itself, because the tests import `ComfyUI_VLM_nodes` as a package and the nodes
|
||||
import ComfyUI's `folder_paths`.
|
||||
|
||||
CI additionally enforces a coverage floor on Linux/Python 3.13:
|
||||
|
||||
```bash
|
||||
python -m pytest -q --cov=nodes --cov-fail-under=70
|
||||
```
|
||||
|
||||
Real-weight tests are opt-in because they download multi-gigabyte checkpoints,
|
||||
and are never run in CI:
|
||||
|
||||
```bash
|
||||
python tests/manual_model_smoke.py --model "Qwen 3 VL 4B Instruct"
|
||||
python tests/manual_specialized_smoke.py --backend florence-large
|
||||
python tests/manual_llama_cpp_smoke.py --download
|
||||
```
|
||||
|
||||
## Writing tests
|
||||
|
||||
Tests must pass without model weights, without a GPU, and without
|
||||
`llama-cpp-python`. Stub the model boundary instead: see
|
||||
`tests/test_suggest.py` and `tests/test_llavaloader.py` for the pattern of
|
||||
faking `LlamaHandle` and `create_chat_completion` to assert what the node sends
|
||||
to the backend.
|
||||
|
||||
`nodes/joytagger/` is vendored upstream code kept byte-compatible with its
|
||||
source. It is excluded from lint; please don't reformat it.
|
||||
|
||||
## Adding a model
|
||||
|
||||
1. Prefer adding an entry to the catalog in `nodes/modern_vlm.py` over a new
|
||||
node. Most current VLMs work through the shared `transformers` path.
|
||||
2. If it needs a bespoke loader, follow `nodes/minicpm.py` as the smallest
|
||||
complete example.
|
||||
3. Register the module in the `node_list` in `__init__.py`.
|
||||
4. Record what you actually ran in `MODEL_VALIDATION.md`. Catalog entries that
|
||||
were never executed against real weights must be marked as such.
|
||||
5. Add the node to the reference table in `README.md`.
|
||||
|
||||
## Releasing
|
||||
|
||||
The Comfy Registry publishes from `pyproject.toml`, and only when `version`
|
||||
changes. A fix merged without a version bump never reaches Registry users. So:
|
||||
|
||||
- bump `version` in `pyproject.toml`,
|
||||
- add a `CHANGELOG.md` entry,
|
||||
- tag the merge commit `vX.Y.Z`.
|
||||
|
||||
## Commit messages
|
||||
|
||||
Short imperative subject, one logical change per commit. Reference the issue it
|
||||
closes in the body.
|
||||
@@ -0,0 +1,186 @@
|
||||
# Model validation
|
||||
|
||||
Validated on 2026-07-29 with ComfyUI 0.28.0, Python 3.12, Transformers 5.14.1,
|
||||
PyTorch 2.13.0+cu126, and an RTX 3090 24 GB. All models and caches were stored
|
||||
on the D drive and executed through WSL.
|
||||
|
||||
## Real-weight passes
|
||||
|
||||
| Family | Representative result | Peak CUDA |
|
||||
| --- | --- | ---: |
|
||||
| Qwen 3.5 | 0.8B BF16 image/video; 0.8B NF4; 2B, 4B, and 9B images | 0.82–17.62 GiB |
|
||||
| Qwen 3 VL | 2B, 4B, and 8B images returned the correct red object | 3.99–16.37 GiB |
|
||||
| SmolVLM2 | 500M image/video and 2.2B video returned the correct object | 2.29–5.41 GiB |
|
||||
| LFM2.5 VL | 450M returned “red … rectangle” | 0.88 GiB |
|
||||
| InternVL 3.5 | 1B video returned “green rectangle” after the 448px patch-grid fix | 2.14 GiB |
|
||||
| Granite Vision 4.1 | 4B returned “solid red square” through native Transformers code | 7.61 GiB |
|
||||
| Florence-2 | Native converted base-FT returned and parsed a bright-red-square caption | 0.59 GiB |
|
||||
| llama.cpp GGUF | Official Qwen3.5-0.8B Q4_0 with llama-cpp-python 0.3.34 CUDA loaded in 20.015s and generated the exact requested response in 0.654s | < 1 GiB model weights |
|
||||
|
||||
One checkpoint covers sibling sizes that use the same architecture and loader.
|
||||
The node does not download every size simply to repeat the same integration
|
||||
test.
|
||||
|
||||
## Robotics VLA pass
|
||||
|
||||
Validated on 2026-07-31 through the included isolated LeRobot HTTP policy
|
||||
server, entirely from WSL and D-drive storage:
|
||||
|
||||
- Runtime: Python 3.12.12, LeRobot 0.6.1 from current upstream source,
|
||||
PyTorch 2.11.0+cu128, and an NVIDIA RTX 3090.
|
||||
- Checkpoint: `lerobot/smolvla_base` (about 2.5 GiB of D-drive cache), backed
|
||||
by `HuggingFaceTB/SmolVLM2-500M-Video-Instruct`.
|
||||
- Real input: local `image (23).png`, a 256x256 outdoor photograph, repeated
|
||||
across the checkpoint's three declared camera keys with a six-value state
|
||||
vector and the task “Move the end effector toward the backpack and prepare
|
||||
to grasp it.”
|
||||
- Contract: three camera tensors, `observation.state`, the LeRobot
|
||||
preprocessor, `predict_action_chunk`, the checkpoint postprocessor, bounded
|
||||
JSON/JPEG transport, action parsing, and the ComfyUI safety layer all ran.
|
||||
The native checkpoint advertises a 50-step chunk; the server returned four
|
||||
steps of six actions for this test.
|
||||
- Five warm requests after one discarded warm-up measured 241.374 ms mean
|
||||
server inference (242.957 ms median, 234.726–249.980 ms range) and
|
||||
270.404 ms mean HTTP client time (271.483 ms median,
|
||||
261.477–282.218 ms range).
|
||||
- The final raw action chunk was:
|
||||
|
||||
```json
|
||||
[
|
||||
[0.06258623, -0.11250310, -0.13713294, -0.06168950, -0.00926633, -0.08506130],
|
||||
[0.15420279, -0.05678255, -0.20159233, 0.06734322, -0.00563951, -0.09575561],
|
||||
[0.16482556, -0.07453565, -0.17410603, 0.02461835, -0.00256573, 0.15842065],
|
||||
[0.27048433, -0.09272483, -0.19934477, 0.05491992, 0.05286619, 0.07594281]
|
||||
]
|
||||
```
|
||||
|
||||
Applying the SO-100/SO-101 template limits from an all-zero previous action
|
||||
found five per-step delta violations, no bounds violations, and no
|
||||
non-finite values. `Clamp safely` produced:
|
||||
|
||||
```json
|
||||
[
|
||||
[0.06258623, -0.1, -0.1, -0.06168950, -0.00926633, -0.08506130],
|
||||
[0.15420279, -0.05678255, -0.2, 0.03831051, -0.00563951, -0.09575561],
|
||||
[0.16482556, -0.07453565, -0.17410603, 0.02461835, -0.00256573, 0.05424440],
|
||||
[0.26482555, -0.09272483, -0.19934477, 0.05491992, 0.05286619, 0.07594281]
|
||||
]
|
||||
```
|
||||
|
||||
This is an end-to-end loading, preprocessing, inference, transport, parsing,
|
||||
and safety-contract pass. It is not evidence that a base SmolVLA checkpoint can
|
||||
control an SO-100 from an arbitrary Internet-style photograph. Actual robot
|
||||
deployment still requires embodiment-matched fine-tuning, calibrated state and
|
||||
camera inputs, hardware-certified limits, a deadman/watchdog, collision
|
||||
handling, and an external emergency stop.
|
||||
|
||||
The same real checkpoint was then exercised through ComfyUI's actual local
|
||||
`POST /prompt` API, not by calling the Python node directly. The graph loaded
|
||||
and center-cropped the real image to 256x256, constructed the three-camera
|
||||
checkpoint contract, called the isolated GPU policy, applied the SO-100/SO-101
|
||||
template safety gate, rendered a 960x480 trajectory preview, and emitted all
|
||||
three text reports. Final prompt
|
||||
`86b31f5a-5a8c-4abc-abdb-634e46da5c93` completed successfully: the policy
|
||||
returned `[4, 6]` actions, the safety gate found three rate violations and
|
||||
clamped them, `safe_for_handoff` was true under the declared template, and
|
||||
ComfyUI wrote preview `ComfyUI_temp_icynu_00001_.png`. The reusable acceptance
|
||||
harness is `tests/manual_robotics_smoke.py`.
|
||||
|
||||
## ComfyUI API pass
|
||||
|
||||
ComfyUI started from the D-drive WSL installation with all four repaired custom
|
||||
node repositories enabled and no custom-node import failures. A real local API
|
||||
workflow (`EmptyImage` -> `ModernVLM` -> `ViewText`) ran the cached LFM2.5-VL
|
||||
450M checkpoint on a solid red input, returned `Red.`, and completed with
|
||||
`unload_after=true`. Prompt ID:
|
||||
`919f92cd-ecb2-487b-abf0-19f5e4d88229`.
|
||||
|
||||
A second real local API workflow (`LLMLoader` -> `LLMSampler` -> `ViewText`)
|
||||
used the official 563 MB `ggml-org/Qwen3.5-0.8B-GGUF` Q4_0 checkpoint with
|
||||
full GPU offload, `n_batch=256`, `n_ubatch=128`, mmap, and Auto flash
|
||||
attention. It returned exactly `ComfyUI llama API ready` and completed
|
||||
successfully. Prompt ID: `eed8458d-de7f-47ac-8ebf-e48e4dacc2d6`.
|
||||
|
||||
The installed llama.cpp CUDA 12.4 wheel reported GPU offload, mmap, and mlock
|
||||
support directly. CPU-only fallback, Metal/Vulkan/SYCL/ROCm-independent
|
||||
capability detection, multi-GPU options, and flash-attention retry are covered
|
||||
by simulated backend contract tests; those vendor kernels were not claimed as
|
||||
real hardware passes on the NVIDIA test machine.
|
||||
|
||||
## Catalog validation
|
||||
|
||||
Configuration and processor resolution passed for all 15 ungated entries in
|
||||
the small/fast catalog: Qwen 3.5 0.8B/2B/4B, Qwen 3 VL 2B/4B, Qwen 2.5 VL 3B,
|
||||
SmolVLM2 256M/500M/2.2B, LFM2.5 VL 450M/1.6B, InternVL 3.5 1B/2B, and Granite
|
||||
Vision 3.3 2B/4.1 4B. Gemma 3 4B is the sixteenth entry and correctly requires
|
||||
license acceptance plus `HF_TOKEN`.
|
||||
|
||||
## Structured vision validation
|
||||
|
||||
The versioned detection/track/point/event payloads, geometry and mask
|
||||
conversion, strict spatial parser, Grounding-family adapters, SAM2.1 session
|
||||
plumbing, SAM3 bit-packed payload adapter, and ByteTrack-style association pass
|
||||
the local WSL contract suite. Those tests validate schemas, shapes, output
|
||||
ordering, bounds, timestamps, deterministic IDs, and error handling.
|
||||
|
||||
Representative real-weight checks were then submitted through ComfyUI's local
|
||||
`POST /prompt` API and verified from `/history/{prompt_id}`. The test machine
|
||||
used ComfyUI 0.28.0, Python 3.12.12, PyTorch 2.13.0+cu126, Transformers 5.14.1,
|
||||
and an NVIDIA RTX 3090. Input media, checkpoints, model caches, ComfyUI, and
|
||||
this checkout all remained on the D drive under WSL.
|
||||
|
||||
| Family | Representative checkpoint policy | Real-weight status |
|
||||
| --- | --- | --- |
|
||||
| Grounding DINO | Tiny; Base uses the same loader/processor contract | **Passed**: FP16, four real 640x360 video frames in two-frame micro-batches; person and bird boxes/labels were visually checked, serialized, timestamped, and in bounds |
|
||||
| OWLv2 | Base Ensemble | Pending |
|
||||
| OmDet Turbo | Swin Tiny | Pending |
|
||||
| SAM2.1 video | Hiera Tiny; sibling sizes use the same session adapter | **Passed**: FP16, real 12-frame 640x360 clip at 24 FPS with CPU preprocessing/state. Grounding's core `BOUNDING_BOX` output connected directly: the forward union-only run kept one person ID on frames 0-11; a last-frame reverse run kept two IDs for 24 observations and emitted 24 frame-major object masks. All geometry was in bounds and first/last overlays and masks were visually checked |
|
||||
| Comfy core SAM3.1 | `sam3.1_multiplex_fp16.safetensors`, only after license/access is available | Pending |
|
||||
| SAM3 adapter/report | Synthetic core payload contract | Passed without weights; real core handoff pending |
|
||||
| ByteTrack-style tracker | Deterministic synthetic crossing, missed-frame, and expiry cases | Passed; no model weights exist |
|
||||
| Florence-2 multitask | Base FT; Large uses the same native Transformers contract | **Passed**: real object-detection API run produced bounded woman, face, and clothing boxes plus a visually checked overlay |
|
||||
|
||||
The SAM2 API check initially exposed a real session-lifecycle defect that unit
|
||||
fixtures did not: prompt insertion must be followed by inference on the seeded
|
||||
frame before propagation. The implementation now performs that seed pass and
|
||||
also propagates in reverse when `seed_frame` is greater than zero. Later live
|
||||
checks exercised nested multi-object core boxes, CPU preprocessing/state,
|
||||
union-only low-memory output, optional object-mask output, disabled preview
|
||||
rendering, reverse propagation, and `unload_after=true` for both models. The
|
||||
final unload run returned total reported GPU memory use to within 4 MiB of the
|
||||
pre-run `nvidia-smi` baseline.
|
||||
|
||||
Grounding DINO and SAM2 sibling sizes are catalog-available but were not
|
||||
downloaded or executed. OWLv2, OmDet Turbo, and gated SAM3 remain explicitly
|
||||
unverified; the UI never presents them as locally tested simply because their
|
||||
schemas import.
|
||||
|
||||
The acceptance run for each model family must record:
|
||||
|
||||
1. Exact checkpoint revision, ComfyUI/Python/PyTorch/Transformers versions,
|
||||
device, dtype, peak accelerator allocation, and wall time.
|
||||
2. A real image or short bounded video with manually verified boxes, labels,
|
||||
masks, timestamps, and stable IDs.
|
||||
3. The canonical JSON schema/version and every advertised output socket,
|
||||
including preview/report output through ComfyUI's local `/prompt` API.
|
||||
4. A second queue using the cached model, followed by an `unload_after=true`
|
||||
run where that option exists.
|
||||
5. Failure behavior for an absent checkpoint or gated access without exposing
|
||||
a token.
|
||||
|
||||
One checkpoint per distinct implementation family is enough for sibling model
|
||||
sizes that share the same code path. Validation prioritizes the smallest useful
|
||||
checkpoint and will not download or execute a 30B model. A larger variant is
|
||||
tested only when it has a different loader, processor, postprocessor, or
|
||||
quantization path.
|
||||
|
||||
## Not marked passed
|
||||
|
||||
- Qwen 3 VL 30B-A3B: weights are available locally, but inference validation
|
||||
was stopped at the user's request and will not be repeated.
|
||||
- Moondream2 2025-06-21: its pinned remote wrapper needed Transformers 5 loading
|
||||
metadata, but this Torch/CUDA stack produced NaN probabilities when sampling
|
||||
and immediate EOS with greedy decoding. The node defaults to the
|
||||
non-destructive greedy path and raises an actionable error on an empty result.
|
||||
- PaLI-Gemma and Gemma 3: gated checkpoints were not accessible without an
|
||||
accepted license and token.
|
||||
@@ -1,94 +1,885 @@
|
||||
<div align="center">
|
||||
<h1> 👁️ VLM Nodes</h1>
|
||||
<p align="center">
|
||||
<b> 🔽Examples below</b> •
|
||||
📙 <a href="https://github.com/gokayfem/Awesome-VLM-Architectures">Visit my other repo to learn more about Vision Language Models</a>
|
||||
</p>
|
||||
</div>
|
||||
<br/>
|
||||
# ComfyUI VLM Nodes
|
||||
|
||||
## Usage
|
||||
Production-oriented vision-language, structured prompting, audio, and utility
|
||||
nodes for ComfyUI. Version 3.4 supports ComfyUI's selected NVIDIA CUDA, AMD
|
||||
ROCm, Apple Metal, Intel XPU, and CPU device without replacing its PyTorch
|
||||
build. It removes startup installers and global accelerator cache flushes,
|
||||
adds real image/video batches and live token streaming, and uses ComfyUI model
|
||||
residency and offloading.
|
||||
|
||||
## VLM Speed Lab
|
||||
|
||||
Performance work is tracked as reproducible, quality-gated iterations in the
|
||||
[VLM Speed Lab](benchmarks/README.md). The first target is the default
|
||||
`Qwen/Qwen3-VL-2B-Instruct`: Transformers baseline, visual-work reduction,
|
||||
Flash Attention 2, compiled execution, SGLang/FlashInfer, and TensorRT-LLM.
|
||||
Every promoted speedup must attach raw outputs and remain inside the declared
|
||||
quality tolerance on the same checkpoint, media, prompts, and decode settings.
|
||||
Planned GPU results stay visibly unreported until a run artifact exists.
|
||||
|
||||
## Modern model coverage
|
||||
|
||||
The **Modern VLM** node provides one stable interface with a deliberately
|
||||
small, 12-choice production picker:
|
||||
|
||||
- Qwen 3.5 0.8B and 4B
|
||||
- Qwen 3 VL 2B, 4B, and 8B Instruct
|
||||
- SmolVLM2 500M and 2.2B Video
|
||||
- Liquid LFM2.5-VL 450M
|
||||
- InternVL 3.5 1B
|
||||
- Granite Vision 4.1 4B
|
||||
- Gemma 3 4B IT
|
||||
- a compatible custom Hugging Face image-to-text repository
|
||||
|
||||
The separate **[Legacy] Modern VLM Compatibility** node contains redundant,
|
||||
superseded, experimental, and very large tiers:
|
||||
|
||||
- Qwen 3.5 2B, 9B, 27B, and 35B-A3B
|
||||
- Qwen 3.6 27B
|
||||
- Qwen 3 VL 30B-A3B Instruct
|
||||
- Qwen 2.5 VL 3B and 7B for existing workflows
|
||||
- Gemma 3 12B and 27B IT
|
||||
- SmolVLM2 256M Video
|
||||
- Liquid LFM2.5-VL 1.6B
|
||||
- InternVL 3.5 2B
|
||||
- Granite Vision 3.3 2B
|
||||
|
||||
Previously saved `ModernVLM` workflows remain valid even when their selected
|
||||
model moved to Legacy. The server accepts every known catalog value for
|
||||
backward compatibility; only the visible new-workflow picker is curated.
|
||||
Dedicated Molmo, PaLI-Gemma, Qwen2-VL, MiniCPM-V, Kosmos-2, MC-LLaVA, UForm,
|
||||
and script-style MoonDream nodes are also collected under
|
||||
`VLM Nodes/Legacy/Model Loaders`. Maintained creator-facing Florence-2,
|
||||
Moondream2, JoyTag, llama.cpp/GGUF, detection, segmentation, tracking, API,
|
||||
and video-intelligence nodes stay in their functional categories.
|
||||
|
||||
Sixteen curated sub-4B/low-VRAM choices are marked internally as the
|
||||
small-and-fast tier. The default is Qwen 3 VL 2B: it is much quicker to load
|
||||
than larger checkpoints while retaining broad image and video understanding.
|
||||
The catalog intentionally uses official model repositories and maintained
|
||||
Transformers interfaces rather than unverified community quantizations.
|
||||
Curated models use native Transformers implementations; remote repository code
|
||||
is enabled only when the explicit custom-model option requires it. Florence-2
|
||||
uses the Transformers-native converted checkpoints instead of Microsoft’s
|
||||
legacy repository code.
|
||||
|
||||
## Live text output
|
||||
|
||||
`Modern VLM` streams decoded text through ComfyUI's native `progress_text`
|
||||
WebSocket channel by default. A connected `ViewText` node updates while tokens
|
||||
arrive, shows the final response after execution, and restores the last result
|
||||
when ComfyUI rehydrates workflow output history. Disable `stream_output` for
|
||||
API-only or headless runs that do not need incremental UI updates. Streaming is
|
||||
best-effort and never changes the final `STRING` output or makes inference fail.
|
||||
|
||||
## Text workflow toolkit
|
||||
|
||||
The original `SimpleText`, `JsonToText`, and `ViewText` node IDs and their
|
||||
first `STRING` outputs remain stable for saved workflows. They now live in
|
||||
organized `VLM Nodes/Text` subcategories and expose descriptive names, search
|
||||
aliases, tooltips, appended metrics, and strict error messages:
|
||||
|
||||
| Node | Purpose |
|
||||
| --- | --- |
|
||||
| `Text` (`SimpleText`) | Multiline/dynamic prompt source with optional edge/newline normalization and character, word, and line outputs |
|
||||
| `View Text (Streaming)` | Read-only live output with counts, copy, UTF-8 download, line wrapping, stream following, reroute traversal, and history rehydration |
|
||||
| `JSON to Text` | Plain or fenced JSON parsing with readable, values-only, key/value, pretty, and compact render modes |
|
||||
| `Text Join` | Join up to eight prompt/context values with empty-value removal and stable deduplication |
|
||||
| `Text Template` | Safe named placeholders from a JSON object plus four convenient live text sockets, with explicit missing-key policy |
|
||||
| `Text Clean` | Unicode NFC/NFKC, newline/whitespace cleanup, enclosing Markdown-fence removal, line deduplication, and deterministic length caps |
|
||||
| `Text Replace` | Literal or regex substitution with case, count, and missing-pattern controls |
|
||||
| `JSON Extract` | JSONPath-lite (`$.items[0]`) and RFC 6901 JSON Pointer extraction from plain or fenced model responses |
|
||||
| `Text Split / Batch` | Lines, paragraphs, delimiters, regex, CSV, or JSON arrays converted to a real mapped Comfy `STRING` list |
|
||||
| `Text Inspector` | Pass-through text plus characters, UTF-8 bytes, words, lines, rough token budget, SHA-256, and JSON metadata |
|
||||
|
||||
The JSON utilities never evaluate code, follow references, access files, or
|
||||
make network requests. Template fields are direct names rather than Python
|
||||
attribute/index expressions. `approx_tokens` is deliberately labeled as a
|
||||
rough UTF-8 budget estimate; use the target model tokenizer when exact billing
|
||||
or context accounting matters.
|
||||
|
||||
Specialized nodes remain available where a generic chat node would discard
|
||||
useful model capabilities:
|
||||
|
||||
- **Moondream 3.1 9B-A2B**: official 2B-active Photon runtime with query,
|
||||
caption, and high-throughput image/video detection and pointing.
|
||||
- **Moondream 3 Preview segment**: native SVG segmentation through the same
|
||||
isolated Photon loader. The SVG is preserved and also converted into antialiased
|
||||
`MASK`, black/white previews, foreground cutouts, overlays, polygons,
|
||||
canonical `VLM_DETECTIONS`, and core bounding boxes. Detection/pointing
|
||||
submit frames concurrently so Photon can dynamically batch them; every run
|
||||
reports measured worker FPS, end-to-end FPS, and real-time factor.
|
||||
- **Florence-2**: captioning, OCR, detection, region captioning, and referring
|
||||
expression segmentation, with structured JSON, mask, and overlay outputs.
|
||||
- **PaLI-Gemma**: caption/VQA plus the official 16-token VQ-VAE segmentation
|
||||
decoder; segmentation tokens are no longer misinterpreted as polygon points.
|
||||
- **Moondream2**: pinned query API with explicit decoding controls. The official
|
||||
checkpoint is loaded through its native safetensors state dict, avoiding the
|
||||
silent empty-output regression in Transformers 5 while retaining ComfyUI
|
||||
managed loading and unloading.
|
||||
- **Qwen2-VL**: image batches and real video-frame batches.
|
||||
- **Legacy Molmo, Kosmos-2, UForm, MCLLaVA, and MiniCPM-V 2.6 GGUF**, plus
|
||||
maintained JoyTag.
|
||||
- **llama.cpp LLaVA/GGUF**, structured prompt suggestions, OpenAI-compatible
|
||||
prompting, and AudioLDM2.
|
||||
|
||||
## Structured detection, segmentation, and tracking
|
||||
|
||||
The vision nodes use stable, typed sockets instead of passing model-specific
|
||||
lists between nodes:
|
||||
|
||||
| Socket | JSON schema | Purpose |
|
||||
| --- | --- | --- |
|
||||
| `VLM_DETECTIONS` | `comfyui-vlm/detections`, version 1 | Per-frame boxes, labels, scores, optional polygons/quads, and in-process masks |
|
||||
| `VLM_TRACKS` | `comfyui-vlm/tracks`, version 1 | Durable object IDs with ordered observations over time |
|
||||
| `VLM_POINTS` | `comfyui-vlm/points`, version 1 | Pixel-coordinate points, including detection centers |
|
||||
| `VLM_EVENTS` | `comfyui-vlm/events`, version 1 | Ordered temporal events for downstream video analysis |
|
||||
| `VLM_VIDEO_SELECTION` | `comfyui-vlm/video-selection`, version 1 | Exact mapping from sampled images to source frame indices and timestamps |
|
||||
| `VLM_SCENE_STATE` | `comfyui-vlm/scene-state`, version 1 | Compact persistent objects, motion, visibility, and validated events |
|
||||
|
||||
All spatial coordinates are source-image pixels. Bounding boxes are
|
||||
`[x1, y1, x2, y2]` with an exclusive right/bottom edge; polygons contain at
|
||||
least three points and quads exactly four. JSON roots contain `schema`,
|
||||
`version`, media dimensions/frame count/FPS, and their ordered records. Dense
|
||||
mask tensors remain in-process and are deliberately omitted from JSON so API
|
||||
results do not unexpectedly grow by hundreds of megabytes.
|
||||
|
||||
The utility layer converts without model-specific glue:
|
||||
|
||||
- `VLMStructuredSpatialParser` strictly parses pixel, normalized 0–1, or
|
||||
normalized 0–1000 JSON from any VLM into `VLM_DETECTIONS` and `VLM_POINTS`.
|
||||
`VLMSpatialPromptBuilder` creates the matching constrained prompt.
|
||||
- `VLMDetectionsToBoundingBoxes`, `VLMDetectionsToPoints`, and
|
||||
`VLMDetectionsToMasks` emit Comfy core boxes, center points, combined and
|
||||
individual binary masks, inverse masks, ready-to-preview black-and-white
|
||||
images, and stable-color instance maps. Polygon/quad masks are rasterized
|
||||
when present, otherwise the bounding box is used. Existing output indexes
|
||||
remain stable; the creator-facing mask images and instance map are appended.
|
||||
- `VLMFilterDetections`, `VLMSelectDetection`, `VLMCropDetections`, and
|
||||
`VLMRenderDetections` provide label/score/area/frame selection, padded crops,
|
||||
and deterministic overlays.
|
||||
- `VLMMaskProcessor` accepts any Comfy `MASK`, including SAM2/SAM3 masks, and
|
||||
returns a feathered matte, strict binary mask, inverse mask, and
|
||||
black-and-white image. Its grow/shrink and Gaussian feathering run in Torch
|
||||
without OpenCV or SciPy.
|
||||
- `VLMMaskComposite` applies still-image or video mask batches to a source and
|
||||
returns the replacement composite, isolated foreground, original
|
||||
background-only plate, and black-and-white mask image. A single mask or
|
||||
background broadcasts safely across a video batch.
|
||||
- `VLMDetectionsFromJSON` and `VLMDetectionsToJSON` are the explicit API and
|
||||
persistence boundary for the versioned detection schema.
|
||||
|
||||
### Universal VLM performance utilities
|
||||
|
||||
The performance nodes sit before any local or hosted VLM, so their savings do
|
||||
not depend on CUDA, ROCm, MPS, XPU, CPU, Transformers, llama.cpp, or Photon:
|
||||
|
||||
- `VLM Performance Profile` emits coherent `max_frames`, pixel budget,
|
||||
longest-edge, batch-size, and `unload_after` values. `Live / robotics`,
|
||||
`Fast video`, `Balanced`, `High detail`, and `Low VRAM handoff` are explicit
|
||||
starting points rather than hidden global flags.
|
||||
- `VLM Adaptive Frame Sampler` is the existing track-aware temporal gate. It
|
||||
combines uniform coverage, scene changes, motion, and optional track changes
|
||||
while preserving source frame indices and timestamps.
|
||||
- `VLM Image Pixel Budget` downsizes the selected analysis copy once, preserves
|
||||
aspect ratio, never upscales, and can align dimensions to 14/28-pixel VLM
|
||||
patches or 32-pixel detector backbones. Fast area and antialiased bicubic
|
||||
modes are available.
|
||||
|
||||
The recommended order is `Video Slice` → `VLM Adaptive Frame Sampler` →
|
||||
`VLM Image Pixel Budget` → any VLM. A model's own official processor still
|
||||
performs its required normalization/crop; the pixel-budget node simply prevents
|
||||
every downstream model from repeatedly receiving unnecessary source pixels.
|
||||
Local torch models remain registered with ComfyUI's smart model manager, while
|
||||
external allocators reserve space before loading and close only the handle they
|
||||
own.
|
||||
|
||||
On the real `vlm_api_people_birds.mp4` input in this repository's D-drive test
|
||||
environment, the utilities selected 10 of 60 1280×720 frames and resized them
|
||||
to 938×518 in about 0.44 seconds on a cold WSL run. That reduced the
|
||||
frame×pixel analysis workload by 11.38× before model inference. This is an
|
||||
input-work reduction measurement, not a claim that every model runs 11.38×
|
||||
faster; token generation and model-specific vision encoders still determine
|
||||
end-to-end speed.
|
||||
|
||||
### Adaptive video intelligence
|
||||
|
||||
The video-intelligence layer keeps generative VLM inference out of the
|
||||
per-frame loop:
|
||||
|
||||
- `VLMAdaptiveFrameSampler` combines scene-change, motion, track-change, and
|
||||
uniform-coverage signals. It always preserves the real source frame index
|
||||
and timestamp, enforces a frame budget, and returns selection/diagnostic
|
||||
JSON. `Uniform coverage`, motion, scene, and track-priority modes remain
|
||||
available for deterministic experiments.
|
||||
- `VLMVideoTemporalReasoner` is the one-node path. It adaptively samples the
|
||||
input, downsizes only the VLM analysis copy (448-pixel longest side by
|
||||
default), runs a recommended video-capable model, parses the result into
|
||||
validated `VLM_EVENTS`, and returns summary, events, selection, sampled
|
||||
previews, raw response, diagnostics, event JSON, and selection JSON.
|
||||
- `VLMVideoReasoningPrompt` and `VLMEventsFromVideoJSON` expose the same strict
|
||||
timestamp/evidence contract for custom local or hosted VLM workflows.
|
||||
- `VLMTrackAwareCrops` chooses representative observations for each durable
|
||||
track, adds configurable context, and letterboxes crops to one batch size.
|
||||
This lets a VLM label identities without rereading every full frame.
|
||||
- `VLMBuildSceneState` converts tracks plus optional events into a compact
|
||||
persistent world-state summary with first/last observation, current box,
|
||||
confidence, state, and pixel velocity.
|
||||
|
||||
Small VLMs commonly return evidence as positions in the supplied image batch
|
||||
even when asked for source indices. The parser accepts that form only when
|
||||
every value is an unambiguous valid supplied-image position, maps it back to
|
||||
the immutable source selection, and records the normalization mode. Arbitrary
|
||||
or unsupplied evidence frames, out-of-range timestamps, invalid confidence,
|
||||
duplicate evidence, malformed JSON, and non-finite values fail validation.
|
||||
|
||||
On the repository's real-data smoke test (RTX 3090, Qwen3-VL 2B, 157-frame
|
||||
896x448 H.264 clip), hybrid sampling selected 12 frames in 0.30 seconds,
|
||||
reduced temporal inputs by 92.36%, reduced analysis pixels by 75%, used
|
||||
4.24 GiB peak allocated VRAM in the standalone runner, and produced a valid
|
||||
timestamped result in 35.17 seconds. The equivalent live ComfyUI `/prompt`
|
||||
graph completed in 37.45 seconds. These are one-machine measurements, not
|
||||
portable performance guarantees.
|
||||
|
||||
### Open-vocabulary image and video detection
|
||||
|
||||
`VLMOpenVocabularyDetection` exposes one interface for:
|
||||
|
||||
- Grounding DINO Tiny and Base
|
||||
- OWLv2 Base Ensemble
|
||||
- OmDet Turbo Swin Tiny
|
||||
|
||||
It accepts a still image or an `IMAGE` batch of video frames and processes the
|
||||
batch frame by frame. Outputs, in socket order, are `detections`, `json`,
|
||||
`preview`, `box_mask`, and Comfy core `bounding_boxes`. Connect the FPS output
|
||||
of `GetVideoComponents` when the input is video so every timestamp is correct.
|
||||
For tracking-by-detection, run detection over the complete bounded batch and
|
||||
connect it to `VLMTrackDetections`.
|
||||
|
||||
`VLMTrackDetections` uses a ByteTrack-style two-stage high/low-confidence
|
||||
association, motion prediction, label-aware matching, and time-based expiry.
|
||||
IDs are durable within the supplied sequence and survive short missed
|
||||
detections when `emit_predictions` is enabled. Independent Comfy queue runs or
|
||||
independently sliced chunks are separate tracking sessions; they do not
|
||||
silently reuse IDs.
|
||||
|
||||
### SAM2.1 and Comfy core SAM3.1
|
||||
|
||||
`VLMSAM2VideoSegmentation` propagates first-frame detections, one core
|
||||
`BOUNDING_BOX`, or seed masks through an `IMAGE` batch using SAM2.1 Hiera Tiny,
|
||||
Small, Base+, or Large. It returns `VLM_TRACKS`, report JSON, per-frame union
|
||||
masks, frame-major individual object masks, and an overlay batch. The object
|
||||
IDs assigned at the seed frame remain stable for that video session.
|
||||
|
||||
`VLMSAM3TrackAdapter` is intentionally an adapter, not a second SAM3 loader. It
|
||||
validates ComfyUI core `SAM3_TRACK_DATA`, preserves the core bit-packed mask
|
||||
payload unchanged, and exposes lightweight `VLM_TRACKS` metadata with mask
|
||||
references. Connect its passthrough output to core `SAM3_TrackPreview` or
|
||||
`SAM3_TrackToMask`, and connect `tracks` to `VLMTrackReport`. This avoids
|
||||
duplicating dense masks in memory or JSON.
|
||||
|
||||
SAM3 weights use Meta's SAM License. The upstream `facebook/sam3` repository
|
||||
requires accepting access terms and sharing the requested account information;
|
||||
the ComfyUI checkpoint is also marked `sam-license`. Review and accept the
|
||||
license before downloading. The example names ComfyUI's
|
||||
`sam3.1_multiplex_fp16.safetensors`; if it is unavailable, use the SAM2.1
|
||||
workflow rather than substituting an unrelated checkpoint.
|
||||
|
||||
### Florence-2 task coverage
|
||||
|
||||
`Florence2` exposes all 15 supported task contracts:
|
||||
|
||||
| Task | Extra input | Structured result |
|
||||
| --- | --- | --- |
|
||||
| Caption | none | text |
|
||||
| Detailed caption | none | text |
|
||||
| More detailed caption | none | text |
|
||||
| OCR | none | text |
|
||||
| OCR with regions | none | text plus quadrilateral regions |
|
||||
| Object detection | none | labeled boxes |
|
||||
| Dense region caption | none | captions with boxes |
|
||||
| Caption to phrase grounding | `text_input` | phrase boxes |
|
||||
| Referring expression segmentation | `text_input` | polygons and mask |
|
||||
| Region to segmentation | one `BOUNDING_BOX` per image | polygons and mask |
|
||||
| Open vocabulary detection | `text_input` | model-provided spatial records |
|
||||
| Region to category | one `BOUNDING_BOX` per image | text |
|
||||
| Region to description | one `BOUNDING_BOX` per image | text |
|
||||
| Region to OCR | one `BOUNDING_BOX` per image | text |
|
||||
| Region proposals | none | boxes |
|
||||
|
||||
Every task returns `text`, `structured_json`, `mask`, and `visualization`.
|
||||
Tasks that do not produce a spatial result return an empty mask and the source
|
||||
image visualization. Region tasks reject ambiguous multi-box input; use
|
||||
`VLMSelectDetection` to isolate the record, then supply exactly one core
|
||||
`BOUNDING_BOX` with the same pixel coordinates.
|
||||
|
||||
### Video memory strategy
|
||||
|
||||
- Trim long media with core `Video Slice`, then use `GetVideoComponents`.
|
||||
Downscale the complete frame batch before detection or segmentation and keep
|
||||
every frame at identical dimensions.
|
||||
- Grounding detection supports configurable micro-batches; keep `batch_size=1`
|
||||
for minimum VRAM or increase it when memory allows. It returns both nested
|
||||
per-frame core `BOUNDING_BOX` values and flat metadata-rich
|
||||
`BOUNDING_BOXES`.
|
||||
- SAM2.1 stores source video frames on CPU, keeps its inference state on CPU by
|
||||
default, and limits the vision-feature cache to one frame. Union masks and
|
||||
previews return on CPU. Full per-object mask volumes are opt-in with
|
||||
`mask_output=union_and_objects`; disable `render_preview` to avoid another
|
||||
full-resolution overlay copy on long clips.
|
||||
- Start with Grounding DINO Tiny plus SAM2.1 Hiera Tiny. Increase detector or
|
||||
segmenter size only after the pipeline is correct. `unload_after=false`
|
||||
caches one model per node instance; use `true` when another large model must
|
||||
run immediately afterward.
|
||||
- A `Video Slice` is an independent propagation session. For very long media,
|
||||
use bounded slices, reseed each slice, and keep the overlap/output mapping in
|
||||
the caller. The pack does not pretend IDs are globally stable across separate
|
||||
queues.
|
||||
- The SAM3 adapter never unpacks the complete mask volume for its report. Use
|
||||
core `SAM3_TrackToMask` only when a dense selected mask is actually needed.
|
||||
|
||||
API-format examples are in [`examples/vision`](examples/vision):
|
||||
|
||||
- [`grounding_dino_image_api.json`](examples/vision/grounding_dino_image_api.json)
|
||||
- [`moondream3_preview_svg_segment_api.json`](examples/vision/moondream3_preview_svg_segment_api.json)
|
||||
- [`moondream31_video_detect_api.json`](examples/vision/moondream31_video_detect_api.json)
|
||||
- [`sam2_video_tracking_api.json`](examples/vision/sam2_video_tracking_api.json)
|
||||
- [`sam3_core_adapter_blueprint_api.json`](examples/vision/sam3_core_adapter_blueprint_api.json)
|
||||
- [`video_temporal_reasoning_api.json`](examples/vision/video_temporal_reasoning_api.json)
|
||||
- [`vlm_performance_preflight_api.json`](examples/vision/vlm_performance_preflight_api.json)
|
||||
|
||||
The dependency-free text-toolkit example is
|
||||
[`examples/text_toolkit_api.json`](examples/text_toolkit_api.json).
|
||||
Robotics policy, safety, and sidecar examples are in
|
||||
[`examples/robotics`](examples/robotics), including a complete universal
|
||||
HTTP policy graph.
|
||||
|
||||
Upload the named media to ComfyUI's input directory, adjust the filenames and
|
||||
labels, then submit the JSON object as the `prompt` value to `/prompt`. These
|
||||
are API graphs, not frontend workflow-export JSON.
|
||||
|
||||
## Node reference
|
||||
|
||||
All 89 registered nodes, grouped by their menu category. The **Node ID** is the
|
||||
`class_type` written into workflow and API JSON — search for that string when
|
||||
you need to find a node you saw on a canvas.
|
||||
|
||||
### Modern VLM
|
||||
|
||||
The main entry point for current vision-language models.
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| Modern VLM (Qwen / SmolVLM2 / LFM / InternVL / Granite / Gemma) | `ModernVLM` | `STRING` |
|
||||
| Moondream 2 | `Moondream2model` | `STRING` |
|
||||
|
||||
### Moondream 3
|
||||
|
||||
Moondream 3 / 3.1 in an isolated Photon runtime. Load once, then reuse the
|
||||
`MOONDREAM31_MODEL` output across the task nodes.
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| Moondream 3 / 3.1 Loader (Isolated Photon) | `Moondream31Loader` | `MOONDREAM31_MODEL`, `STRING` |
|
||||
| Moondream 3 / 3.1 Caption | `Moondream31Caption` | `STRING`, `STRING` |
|
||||
| Moondream 3 / 3.1 Query | `Moondream31Query` | `STRING`, `STRING`, `STRING` |
|
||||
| Moondream 3 / 3.1 Detect (Image / Video) | `Moondream31Detect` | `VLM_DETECTIONS`, `STRING`, `IMAGE`, `MASK`, `BOUNDING_BOX`, `BOUNDING_BOXES`, `STRING` |
|
||||
| Moondream 3 / 3.1 Point (Image / Video) | `Moondream31Point` | `VLM_POINTS`, `STRING`, `IMAGE`, `STRING` |
|
||||
| Moondream 3 Preview SVG Segment (Image / Video) | `Moondream31Segment` | `VLM_DETECTIONS`, `STRING`, `STRING`, `MASK`, `IMAGE`, `IMAGE`, `IMAGE`, `BOUNDING_BOX`, `BOUNDING_BOXES`, `STRING` |
|
||||
|
||||
### Florence-2
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| Florence-2 Multitask Vision | `Florence2` | `STRING`, `STRING`, `MASK`, `IMAGE` |
|
||||
|
||||
### Vision: detection, segmentation, tracking
|
||||
|
||||
Open-vocabulary detection and video segmentation. These emit the structured
|
||||
`VLM_DETECTIONS` / `VLM_POINTS` / `VLM_TRACKS` types rather than loose strings.
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| VLM Open-Vocabulary Detection | `VLMOpenVocabularyDetection` | `VLM_DETECTIONS`, `STRING`, `IMAGE`, `MASK`, `BOUNDING_BOX`, `BOUNDING_BOXES` |
|
||||
| VLM SAM2.1 Video Segmentation | `VLMSAM2VideoSegmentation` | `VLM_TRACKS`, `STRING`, `MASK`, `MASK`, `IMAGE` |
|
||||
| VLM SAM3 Track Adapter | `VLMSAM3TrackAdapter` | `VLM_TRACKS`, `SAM3_TRACK_DATA` |
|
||||
| VLM Track Detections | `VLMTrackDetections` | `VLM_TRACKS` |
|
||||
| VLM Track Report | `VLMTrackReport` | `STRING`, `STRING` |
|
||||
| JoyTag | `Joytag` | `STRING` |
|
||||
|
||||
### Vision: spatial reasoning
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| VLM Spatial Prompt Builder | `VLMSpatialPromptBuilder` | `STRING` |
|
||||
| VLM Structured Spatial Parser | `VLMStructuredSpatialParser` | `VLM_DETECTIONS`, `VLM_POINTS`, `STRING` |
|
||||
|
||||
### Vision: detection utilities
|
||||
|
||||
Converters and filters between structured detections and ordinary Comfy types.
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| Filter VLM Detections | `VLMFilterDetections` | `VLM_DETECTIONS` |
|
||||
| Select VLM Detection | `VLMSelectDetection` | `VLM_DETECTIONS` |
|
||||
| Crop VLM Detections | `VLMCropDetections` | `IMAGE`, `STRING` |
|
||||
| Render VLM Detections | `VLMRenderDetections` | `IMAGE` |
|
||||
| VLM Detection Centers | `VLMDetectionsToPoints` | `VLM_POINTS`, `STRING` |
|
||||
| VLM Detections from JSON | `VLMDetectionsFromJSON` | `VLM_DETECTIONS` |
|
||||
| VLM Detections to JSON | `VLMDetectionsToJSON` | `STRING` |
|
||||
| VLM Detections to Bounding Boxes | `VLMDetectionsToBoundingBoxes` | `BOUNDING_BOXES`, `STRING` |
|
||||
| VLM Detections to Masks | `VLMDetectionsToMasks` | `MASK`, `MASK`, `STRING`, `MASK`, `IMAGE`, `IMAGE`, `IMAGE` |
|
||||
|
||||
### Vision: mask tools
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| VLM Mask Processor | `VLMMaskProcessor` | `MASK`, `MASK`, `MASK`, `IMAGE` |
|
||||
| VLM Mask Composite | `VLMMaskComposite` | `IMAGE`, `IMAGE`, `IMAGE`, `IMAGE` |
|
||||
|
||||
### Video intelligence
|
||||
|
||||
Adaptive frame selection and temporal reasoning for long videos.
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| VLM Adaptive Frame Sampler | `VLMAdaptiveFrameSampler` | `IMAGE`, `VLM_VIDEO_SELECTION`, `STRING`, `STRING` |
|
||||
| VLM Video Reasoning Prompt | `VLMVideoReasoningPrompt` | `STRING`, `STRING` |
|
||||
| VLM Video Temporal Reasoner | `VLMVideoTemporalReasoner` | `STRING`, `VLM_EVENTS`, `VLM_VIDEO_SELECTION`, `IMAGE`, `STRING`, `STRING`, `STRING`, `STRING` |
|
||||
| VLM Temporal Events From JSON | `VLMEventsFromVideoJSON` | `VLM_EVENTS`, `STRING`, `STRING` |
|
||||
| VLM Persistent Scene State | `VLMBuildSceneState` | `VLM_SCENE_STATE`, `STRING`, `STRING` |
|
||||
| VLM Track-Aware Semantic Crops | `VLMTrackAwareCrops` | `IMAGE`, `STRING` |
|
||||
|
||||
### LLM (local GGUF)
|
||||
|
||||
llama.cpp text models. `LLM Loader (GGUF)` produces the `CUSTOM` model handle
|
||||
the samplers consume; the *Managed Cache* variants own their own handle and can
|
||||
release it after each run.
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| LLM Loader (GGUF) | `LLMLoader` | `CUSTOM` |
|
||||
| LLM Sampler | `LLMSampler` | `STRING` |
|
||||
| LLM Prompt Generator | `LLMPromptGenerator` | `STRING` |
|
||||
| LLM (Managed Cache) | `LLMOptionalMemoryFreeSimple` | `STRING` |
|
||||
| LLM (Managed Cache, Advanced) | `LLMOptionalMemoryFreeAdvanced` | `STRING` |
|
||||
| Structured Output | `StructuredOutput` | `STRING` |
|
||||
| Structured Keyword Extraction | `KeywordExtraction` | `STRING` |
|
||||
| Structured Prompt Generator | `LLavaPromptGenerator` | `STRING` |
|
||||
| Creative Art Prompt Generator | `CreativeArtPromptGenerator` | `STRING` |
|
||||
| Prompt Suggester | `Suggester` | `STRING` |
|
||||
|
||||
### LLaVA (local GGUF multimodal)
|
||||
|
||||
Vision models through llama.cpp. These need both a GGUF and its vision
|
||||
projector (mmproj).
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| LLaVA Loader | `LLava Loader Simple` | `CUSTOM` |
|
||||
| LLaVA Vision Projector Loader | `LlavaClipLoader` | `CUSTOM` |
|
||||
| LLaVA Sampler | `LLavaSamplerSimple` | `STRING` |
|
||||
| LLaVA Sampler (Advanced) | `LLavaSamplerAdvanced` | `STRING` |
|
||||
| LLaVA (Managed Cache) | `LLavaOptionalMemoryFreeSimple` | `STRING` |
|
||||
| LLaVA (Managed Cache, Advanced) | `LLavaOptionalMemoryFreeAdvanced` | `STRING` |
|
||||
|
||||
### Hosted APIs
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| Hosted VLM API (Secure) | `HostedVLMAPI` | `STRING`, `STRING`, `INT` |
|
||||
| Hosted LLM API (Secure) | `PromptGenerateAPI` | `STRING` |
|
||||
|
||||
### Robotics / VLA policies
|
||||
|
||||
These nodes build and inspect policy observations/actions. They never send
|
||||
commands to robot hardware. Heavy policy runtimes stay in isolated LeRobot,
|
||||
openpi, GR00T, OpenVLA/OFT, or JAX environments.
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| VLA Embodiment Profile | `VLAEmbodimentProfile` | `VLA_EMBODIMENT`, `STRING`, `INT`, `INT` |
|
||||
| VLA Observation Builder | `VLAObservationBuilder` | `VLA_OBSERVATION`, `STRING`, `INT` |
|
||||
| VLA Policy — Universal HTTP | `VLAHTTPPolicy` | `VLA_ACTIONS`, `STRING` |
|
||||
| VLA Policy — OpenPI WebSocket | `VLAOpenPIWebSocketPolicy` | `VLA_ACTIONS`, `STRING` |
|
||||
| VLA Policy — GR00T N1.7 ZMQ | `VLAGr00tZMQPolicy` | `VLA_ACTIONS`, `STRING` |
|
||||
| VLA Action Safety Gate | `VLAActionSafety` | `VLA_ACTIONS`, `STRING`, `BOOLEAN` |
|
||||
| VLA Actions From JSON | `VLAActionsFromJSON` | `VLA_ACTIONS`, `STRING` |
|
||||
| VLA Action Chunk Replan | `VLAActionChunkReplan` | `VLA_ACTIONS`, `STRING` |
|
||||
| VLA Action Inspect | `VLAActionInspect` | `STRING`, `STRING`, `INT`, `INT` |
|
||||
| VLA Trajectory Preview | `VLATrajectoryPreview` | `IMAGE` |
|
||||
| VLA Model Catalog | `VLAModelCatalog` | `STRING`, `STRING`, `STRING`, `STRING` |
|
||||
|
||||
### Text toolkit
|
||||
|
||||
Dependency-free string handling, so a VLM response can be shaped without an
|
||||
extra node pack.
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| Text | `SimpleText` | `STRING`, `INT`, `INT`, `INT` |
|
||||
| Text Join | `VLMTextJoin` | `STRING`, `STRING`, `INT` |
|
||||
| Text Template | `VLMTextTemplate` | `STRING`, `STRING`, `STRING` |
|
||||
| Text Clean | `VLMTextClean` | `STRING`, `STRING` |
|
||||
| Text Replace | `VLMTextReplace` | `STRING`, `INT`, `STRING` |
|
||||
| Text Split / Batch | `VLMTextSplit` | `STRING`, `STRING`, `INT` |
|
||||
| Text Inspector | `VLMTextInspect` | `STRING`, `INT`, `INT`, `INT`, `INT`, `INT`, `STRING`, `STRING` |
|
||||
| View Text (Streaming) | `ViewText` | `STRING`, `INT`, `INT`, `INT`, `STRING` |
|
||||
| JSON Extract | `VLMJSONExtract` | `STRING`, `BOOLEAN`, `STRING`, `STRING` |
|
||||
| JSON to Text | `JsonToText` | `STRING`, `STRING`, `INT` |
|
||||
|
||||
### Performance and diagnostics
|
||||
|
||||
Run **VLM Runtime Diagnostics** before reporting a bug — it reports your
|
||||
device, backend, and which optional packages are installed.
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| VLM Runtime Diagnostics | `VLMRuntimeDiagnostics` | `STRING` |
|
||||
| VLM Performance Profile | `VLMPerformanceProfile` | `INT`, `FLOAT`, `INT`, `INT`, `BOOLEAN`, `STRING` |
|
||||
| VLM Image Pixel Budget | `VLMImagePixelBudget` | `IMAGE`, `INT`, `INT`, `STRING` |
|
||||
|
||||
### Audio
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| AudioLDM2 | `AudioLDM2Node` | `*`, `INT`, `AUDIO` |
|
||||
| Chat Musician | `ChatMusician` | `STRING`, `*`, `INT`, `AUDIO` |
|
||||
| MiniMax Music | `MiniMaxMusicNode` | `*`, `INT`, `AUDIO` |
|
||||
| PlayMusic Node | `PlayMusic` | `*` |
|
||||
| Save Audio | `SaveAudioNode` | — |
|
||||
|
||||
MiniMax Music reads `MINIMAX_API_KEY` only from the ComfyUI server
|
||||
environment. It uses fixed `global_en` and `cn_zh` endpoints, supports music
|
||||
generation and cover models, decodes URL or hexadecimal responses, and emits
|
||||
MP3, WAV, or PCM results through the existing waveform and `AUDIO` sockets.
|
||||
The `aigc_watermark` field is sent only for `cn_zh` requests. See the official
|
||||
[global](https://platform.minimax.io/docs/api-reference/music-generation) or
|
||||
[China](https://platform.minimaxi.com/docs/api-reference/music-generation)
|
||||
music API reference for account and content requirements.
|
||||
|
||||
### Legacy model loaders
|
||||
|
||||
Kept for existing workflows. New graphs should prefer **Modern VLM**, which
|
||||
covers most of these architectures through one interface.
|
||||
|
||||
| Node | Node ID | Outputs |
|
||||
| --- | --- | --- |
|
||||
| Qwen2-VL | `Qwen2VLNode` | `STRING` |
|
||||
| MiniCPM-V 2.6 (GGUF) | `MiniCPMNode` | `STRING` |
|
||||
| Molmo Vision-Language Model | `MolmoNode` | `STRING` |
|
||||
| PaLI-Gemma (Official Segmentation) | `Paligemma` | `STRING`, `MASK`, `IMAGE` |
|
||||
| Kosmos-2 | `Kosmos2model` | `STRING` |
|
||||
| MC-LLaVA | `MCLLaVAModel` | `STRING` |
|
||||
| UForm Gen2 Qwen | `UformGen2QwenNode` | `STRING` |
|
||||
| MoonDream (Moondream 2) | `MoonDream` | `STRING` |
|
||||
| [Legacy] Modern VLM Compatibility | `LegacyModernVLM` | `STRING` |
|
||||
|
||||
## Install
|
||||
|
||||
Install through ComfyUI Manager, or clone into `ComfyUI/custom_nodes` and run:
|
||||
|
||||
```bash
|
||||
python -m pip install -r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements.txt
|
||||
```
|
||||
cd custom_nodes
|
||||
git clone https://github.com/gokayfem/ComfyUI_VLM_nodes.git
|
||||
|
||||
Run that command with ComfyUI's Python. Do not install or replace `torch` from
|
||||
this repository: ComfyUI's own installer selects CUDA, ROCm, XPU, Metal, or CPU.
|
||||
Current official bitsandbytes wheels are installed automatically only on their
|
||||
supported OS/architecture combinations. Unsupported machines retain all
|
||||
non-quantized nodes.
|
||||
|
||||
### Robotics / VLA isolated runtimes
|
||||
|
||||
The robotics nodes keep policy dependencies outside ComfyUI. The universal
|
||||
HTTP client works without another package. Native openpi WebSocket and
|
||||
GR00T ZeroMQ clients use the lightweight optional extra:
|
||||
|
||||
```bash
|
||||
python -m pip install \
|
||||
-r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements-robotics-client.txt
|
||||
```
|
||||
## VLM Nodes
|
||||
Utilizes ```llama-cpp-python``` for integration of LLaVa models. You can load and use any VLM with LLaVa models in GGUF format with this nodes.
|
||||
You need to download the model similar to ```ggml-model-q4_k.gguf``` and it's clip projector similar to ```mmproj-model-f16.gguf``` from this repositories (in the files and versions).
|
||||
```python=>3.9``` is necessary.
|
||||
Put all of the files inside ```models/LLavacheckpoints```
|
||||
Note that every **model's clip projector** is different!
|
||||
- [LlaVa 1.6 Mistral 7B](https://huggingface.co/cjpais/llava-1.6-mistral-7b-gguf/)
|
||||
- [Nous Hermes 2 Vision](https://huggingface.co/billborkowski/llava-NousResearch_Nous-Hermes-2-Vision-GGUF)
|
||||
- [LlaVa 1.5 7B](https://huggingface.co/mys/ggml_llava-v1.5-7b/)
|
||||
- [LlaVa 1.5 13B](https://huggingface.co/mys/ggml_llava-v1.5-13b)
|
||||
- [BakLLaVa](https://huggingface.co/mys/ggml_bakllava-1)
|
||||
etc..
|
||||
## InternLM-XComposer2-VL Node
|
||||
Utilizes ```AutoGPTQ``` for integration of InternLM-XComposer2-VL Model. It will automatically download the necessary files into ```custom_nodes/ComfyUI_VLM_nodes/nodes/files_for_internlm```.
|
||||
This is one of the best models for visual perception.
|
||||
**Important Note : This model is heavy.**
|
||||
- [InternLM-XComposer2](https://huggingface.co/internlm/internlm-xcomposer2-vl-7b-4bit)
|
||||
|
||||
## Automatic Prompt Generation and Suggestion Nodes
|
||||
**Get Keyword** node: It can take LLava outputs and extract keywords from them.
|
||||
**LLava PromptGenerator** node: It can create prompts given descriptions or keywords using (input prompt could be Get Keyword or LLava output directly).
|
||||
**Suggester** node: It can generate 5 different prompts based on the original prompt using consistent in the options or random prompts using random in the options.
|
||||
Works best with **LLava 1.5** and **1.6**.
|
||||
`VLA Model Catalog` covers current SmolVLA, X-VLA, π0/π0-FAST/π0.5,
|
||||
GR00T N1.7, WALL-OSS, MolmoAct2, VLA-JEPA, LingBot-VA, FastWAM, EO-1,
|
||||
EVO-1, OpenVLA-OFT, and Octo routes. “Available” means a supported isolated
|
||||
runtime/checkpoint path; base and architecture-only entries still require
|
||||
embodiment-specific training and transforms.
|
||||
|
||||
**Play with the ```temperature``` for creative or consistent results. Higher the temperature more creative are the results.**
|
||||
If you want to dive deep into [LLM Settings](https://www.promptingguide.ai/introduction/settings)
|
||||
Start with SmolVLA for small consumer hardware. The included authenticated
|
||||
LeRobot sidecar loads one chosen policy, uses its serialized processors,
|
||||
returns action chunks over bounded JSON/JPEG, keeps it resident for speed,
|
||||
and can offload it to CPU after an idle timeout. Remote policy URLs require
|
||||
encrypted transport and explicit opt-in. Tokens are fixed environment
|
||||
variables (`VLA_POLICY_TOKEN`, `OPENPI_API_KEY`, or `GROOT_API_TOKEN`) and are
|
||||
never workflow inputs.
|
||||
|
||||
Outputs are JSON looking texts, you can see them as a text using JsonToText Node.
|
||||
You can see any string output with ViewText Node
|
||||
You can set any string input using SimpleText Node
|
||||
Utilizes ```llama-cpp-agents``` for getting structured outputs.
|
||||
## LLM Prompt Generation from text nodes
|
||||
See [`examples/robotics/README.md`](examples/robotics/README.md) for D-drive
|
||||
WSL setup, platform boundaries, current model readiness, observation schemas,
|
||||
action safety semantics, and the runnable API example.
|
||||
|
||||
**LLM PromptGenerator** node:
|
||||
[Qwen 1.8B Stable Diffusion Prompt](https://huggingface.co/hahahafofo/Qwen-1_8B-Stable-Diffusion-Prompt-GGUF)
|
||||
[IF prompt MKR](https://huggingface.co/impactframes/IFpromptMKR-7b-L2-gguf-q4_k_m)
|
||||
This LLM's works best for now for prompt generation.
|
||||
**LLMSampler** node: You can chat with any LLM in gguf format, you can use LLava models as an LLM also.
|
||||
### Moondream 3 / 3.1 isolated runtime
|
||||
|
||||
**API PromptGenerator** node: You can use ChatGPT and DeepSeek API's to create prompts. https://platform.deepseek.com/ gives 10m free tokens.
|
||||
- ChatGPT-4
|
||||
- ChatGPT-3.5
|
||||
- DeepSeek
|
||||
You can use them for simple chat also there is an option in the node.
|
||||
Moondream's official Photon package pins Pillow below version 11 while
|
||||
current ComfyUI uses a newer Pillow. It therefore runs in a dedicated sidecar
|
||||
environment and never changes ComfyUI's Python packages. Read and accept the
|
||||
[Moondream Model License 1.0](https://moondream.ai/licenses/model/1.0), then
|
||||
create the environment under the registered `LLavacheckpoints` model folder.
|
||||
|
||||
## moondream Node
|
||||
This node is designed to work with the Moondream model, a powerful small vision language model built by @vikhyatk using SigLIP, Phi-1.5, and the LLaVa training dataset.
|
||||
The model boasts 1.6 billion parameters and is made available for research purposes only; commercial use is not allowed.
|
||||
It will automatically download the necessary files into ```custom_nodes/ComfyUI_VLM_nodes/nodes/files_for__moondream```
|
||||
## JoyTag Node
|
||||
@fpgamine's JoyTag is a state of the art AI vision model for tagging images, with a focus on sex positivity and inclusivity.
|
||||
It uses the Danbooru tagging schema, but works across a wide range of images, from hand drawn to photographic.
|
||||
It will automatically download the necessary files into ```custom_nodes/ComfyUI_VLM_nodes/nodes/files_for_joytagger```
|
||||
## Example LLaVa Nodes
|
||||
|
||||
Linux/WSL/macOS:
|
||||
|
||||
## Example InternLM-XComposer Node
|
||||
|
||||
```bash
|
||||
runtime="ComfyUI/models/LLavacheckpoints/moondream31-runtime"
|
||||
uv venv "$runtime/.venv" --python 3.12
|
||||
uv pip install --python "$runtime/.venv/bin/python" \
|
||||
-r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements-moondream31.txt
|
||||
```
|
||||
|
||||
## Example Using Automatic Prompt Generation
|
||||
|
||||
Windows PowerShell:
|
||||
|
||||
## LLM Nodes
|
||||

|
||||
```powershell
|
||||
$runtime = "ComfyUI\models\LLavacheckpoints\moondream31-runtime"
|
||||
uv venv "$runtime\.venv" --python 3.12
|
||||
uv pip install --python "$runtime\.venv\Scripts\python.exe" `
|
||||
-r "ComfyUI\custom_nodes\ComfyUI_VLM_nodes\requirements-moondream31.txt"
|
||||
```
|
||||
|
||||
## Example moondream
|
||||
|
||||
The first Loader execution downloads the selected official model below that
|
||||
runtime's `cache` directory. Use `moondream3.1-9B-A2B` for query, caption,
|
||||
detection, and pointing. Use `moondream3-preview` only for the SVG segment
|
||||
skill; the final 3.1 model card does not list segment. Set the server-side
|
||||
`MOONDREAM_PYTHON` environment variable
|
||||
when using a different isolated environment. Do not put this path or any
|
||||
credential in a workflow.
|
||||
|
||||
## Example Joytag
|
||||

|
||||
Official Photon local inference currently supports NVIDIA Ampere-or-newer on
|
||||
Linux/Windows and Apple Silicon on macOS 13 or newer. It does not currently
|
||||
provide local ROCm, Intel GPU, or CPU execution. Those platforms retain every
|
||||
portable Transformers, GGUF, API, and vision utility node in this pack.
|
||||
|
||||
## Example Prompt Generation
|
||||
|
||||
On CUDA 12 x86-64 systems the isolated requirements deliberately install
|
||||
`nvidia-cuda-runtime-cu12==12.9.79`. Kestrel 0.4.6's AOT kernels require the
|
||||
`cudaLibraryLoadData` entry point, which is absent from the CUDA 12.6 runtime
|
||||
bundled by cu126 PyTorch. This pin updates only Photon's private runtime; it
|
||||
does not replace ComfyUI's PyTorch build or the host NVIDIA driver.
|
||||
|
||||
## Example SimpleChat
|
||||
|
||||
GGUF nodes use optional `llama-cpp-python`. Install a wheel built for the
|
||||
desired CUDA, ROCm/HIP, Metal, Vulkan, SYCL, or CPU backend:
|
||||
|
||||
## Example LLava Sampler Advanced
|
||||
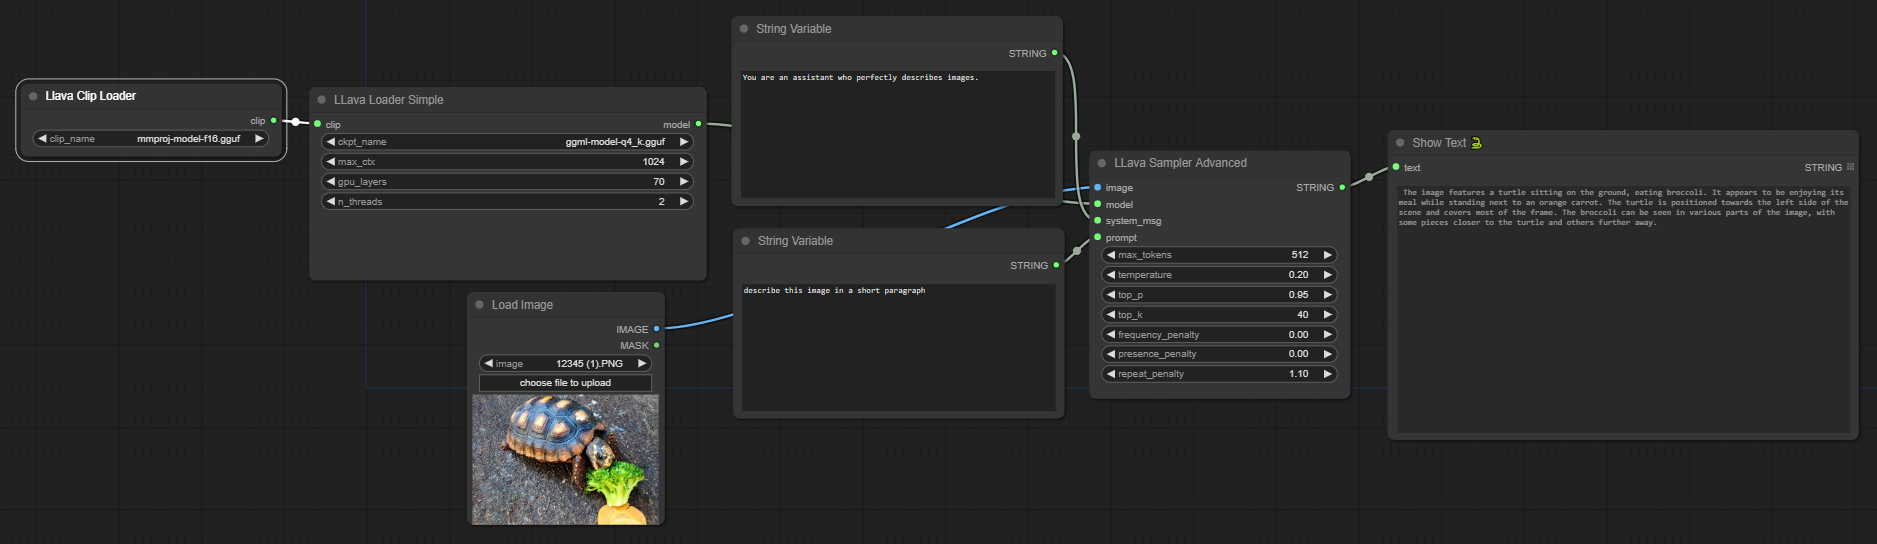
|
||||
```bash
|
||||
python -m pip install -r ComfyUI/custom_nodes/ComfyUI_VLM_nodes/requirements-llama-cpp.txt
|
||||
```
|
||||
|
||||
See [COMPATIBILITY.md](COMPATIBILITY.md) for the tested matrix and official
|
||||
backend-specific GGUF commands.
|
||||
|
||||
The GGUF loaders now query the installed llama.cpp build instead of inferring
|
||||
its capabilities from PyTorch. Accelerator offload automatically falls back to
|
||||
CPU when a CPU-only wheel is installed. Advanced optional inputs expose logical
|
||||
and physical prompt batching (`n_batch`/`n_ubatch`), flash-attention policy,
|
||||
mmap, and CUDA/ROCm multi-GPU layer/row splitting without changing legacy
|
||||
workflow sockets. `Auto` flash attention retries the portable path if a
|
||||
backend/model pair rejects it.
|
||||
|
||||
The **LLaVA Vision Projector Loader** supports metadata-driven MTMD plus
|
||||
explicit handlers for LLaVA 1.5/1.6, MiniCPM-V 2.6, Moondream2, NanoLLaVA,
|
||||
Qwen2.5-VL, Gemma 4, Llama 3 Vision Alpha, and Obsidian. Use the default
|
||||
metadata-driven handler for current GGUF + mmproj pairs; select the named
|
||||
legacy handler when a model card requires it.
|
||||
|
||||
Models are downloaded only when their node first executes and are stored below
|
||||
`ComfyUI/models/LLavacheckpoints`. Hugging Face downloads respect `HF_TOKEN`.
|
||||
Gemma 3 and PaLI-Gemma require accepting their model licenses on Hugging Face.
|
||||
|
||||
## GPU lifecycle
|
||||
|
||||
- **ComfyUI managed (BF16)** is the default and preferred path. BF16 is used
|
||||
only when the active device reports support; otherwise the node safely falls
|
||||
back to FP16 on CUDA/ROCm/Metal/XPU or FP32 on CPU.
|
||||
- **4-bit/8-bit** models and llama.cpp own external allocators. Before loading,
|
||||
the nodes ask ComfyUI to free the required space; unloading closes the exact
|
||||
owned model and then requests a soft cache cleanup. Small quantized models
|
||||
stay on ComfyUI's active device instead of assuming GPU zero. Large-model
|
||||
Accelerate placement is enabled on CUDA/ROCm/XPU; any disk offload remains
|
||||
inside the model's ComfyUI directory.
|
||||
- llama.cpp model and projector bytes are included in the pre-load reservation.
|
||||
The runtime reports llama.cpp's own compiled backend, GPU-offload, mmap, and
|
||||
mlock capabilities in **VLM Runtime Diagnostics**.
|
||||
- `unload_after=false` caches one model per node instance for fast repeated
|
||||
queues. Cache creation is serialized, so concurrent API work cannot make the
|
||||
same node allocate duplicate model handles. Turn it on for maximum
|
||||
reclamation between prompts.
|
||||
- Moondream Photon asks ComfyUI to make room before it starts, then owns one
|
||||
exact isolated process. `unload_after=true` gracefully shuts it down and
|
||||
terminates that process if necessary, which releases Photon model, KV-cache,
|
||||
and CUDA-graph allocations without flushing unrelated ComfyUI models. The
|
||||
sidecar intentionally does not inherit ComfyUI's PyTorch allocator override;
|
||||
Photon's CUDA-graph capture uses the native allocator in its own process. The
|
||||
worker does not inherit unrelated provider keys or proxy credentials; only
|
||||
`HF_TOKEN`, and `MOONDREAM_API_KEY` for an explicitly selected adapter, may
|
||||
cross into its server-side environment. Base-model sidecars honor
|
||||
`DO_NOT_TRACK` locally and do not start Kestrel's anonymous telemetry task.
|
||||
Its random IPC secret is not placed on the process command line.
|
||||
- A connected `video_frames` batch becomes the primary visual input. The
|
||||
optional still-image socket is ignored for video inference so smaller models
|
||||
cannot silently answer from the wrong media.
|
||||
- Qwen 3.5/3.6 thinking is off by default for lower latency and predictable
|
||||
output length; enable it explicitly for tasks that benefit from visual
|
||||
reasoning.
|
||||
- **Auto (SDPA)** is portable and preferred. Flash Attention 2 is accepted only
|
||||
on supported CUDA/ROCm builds and otherwise fails before model loading.
|
||||
- **VLM Runtime Diagnostics** produces a zero-download JSON report containing
|
||||
OS, Python, PyTorch, backend, dtype capability, and optional package versions.
|
||||
- Visualization-only companion repositories do not allocate accelerator memory.
|
||||
|
||||
Avoid placing several independently quantized VLMs in one workflow unless the
|
||||
GPU can hold them. On a 24 GB card, Qwen 3 VL 2B is the fast default,
|
||||
Qwen 3 VL 8B fits in BF16, and larger models should use NF4. Qwen 3.5/3.6 can
|
||||
be substantially slower when their optional optimized linear-attention kernels
|
||||
are not available for the installed PyTorch/backend combination.
|
||||
|
||||
## API nodes
|
||||
|
||||
**Hosted LLM API (Secure)** and **Hosted VLM API (Secure)** share a provider
|
||||
layer built around the current OpenAI Responses and Chat Completions request
|
||||
shapes, with Anthropic using its native Messages/vision contract and Gemini
|
||||
switching to its native multimodal contract for grounded or structured calls.
|
||||
The VLM node
|
||||
accepts a still image or a video-frame batch, samples
|
||||
frames uniformly, resizes and JPEG-compresses them, and enforces per-image and
|
||||
total request limits before upload. Both nodes can stream text into a connected
|
||||
`ViewText` node.
|
||||
|
||||
Both API nodes also expose:
|
||||
|
||||
- **Native web search** for OpenAI, Gemini, Anthropic, xAI, and any compatible
|
||||
model routed through OpenRouter. Unsupported presets fail clearly before a
|
||||
model request instead of silently pretending to search. Search can add
|
||||
provider cost and has provider-specific data terms, so it is off by default.
|
||||
- **JSON object** and **JSON Schema** output. Completed JSON is always parsed
|
||||
locally, JSON Schema results are validated locally, and invalid results fail
|
||||
the node instead of flowing into downstream automation.
|
||||
- **Open-source structured VLM output** through Custom / Local endpoints.
|
||||
OpenAI-standard mode supports vLLM, Ollama, and compatible servers;
|
||||
`llama.cpp JSON Schema` emits llama.cpp's direct schema dialect; and
|
||||
`JSON object + local validation` is a portable fallback for servers that
|
||||
implement only JSON mode.
|
||||
|
||||
User-provided schemas are capped at 64,000 characters, bounded by depth/node
|
||||
count, checked against their declared JSON Schema draft, and may use only local
|
||||
fragment `$ref` values. Remote/file references are rejected so validation can
|
||||
never turn into an unexpected network or filesystem lookup.
|
||||
|
||||
Curated production profiles include:
|
||||
|
||||
| Provider | Presets | Server environment variable |
|
||||
| --- | --- | --- |
|
||||
| OpenAI | GPT-5.6 Terra, Sol, Luna | `OPENAI_API_KEY` |
|
||||
| Google | Gemini 3.6 Flash, 3.5 Flash, 3.5 Flash-Lite | `GEMINI_API_KEY` |
|
||||
| Anthropic | Claude Fable 5, Opus 5, Sonnet 5, Haiku 4.5 | `ANTHROPIC_API_KEY` |
|
||||
| xAI | Grok 4.5 | `XAI_API_KEY` |
|
||||
| DeepSeek | V4 Flash, V4 Pro | `DEEPSEEK_API_KEY` |
|
||||
| Groq | Qwen 3.6 27B Vision, GPT-OSS 20B | `GROQ_API_KEY` |
|
||||
| Mistral | Mistral Large, Mistral Small, Ministral 14B | `MISTRAL_API_KEY` |
|
||||
| Together AI | Kimi K2.5, Qwen 3.5 9B | `TOGETHER_API_KEY` |
|
||||
| OpenRouter | Any compatible model ID | `OPENROUTER_API_KEY` |
|
||||
| Custom/local | OpenAI-compatible endpoint | `CUSTOM_API_KEY` |
|
||||
|
||||
Preset IDs were reviewed on 2026-07-29 against the official
|
||||
[OpenAI](https://developers.openai.com/api/docs/models),
|
||||
[Gemini](https://ai.google.dev/gemini-api/docs/models),
|
||||
[Claude](https://platform.claude.com/docs/en/about-claude/models/overview),
|
||||
[xAI](https://docs.x.ai/developers/models),
|
||||
[DeepSeek](https://api-docs.deepseek.com/updates/),
|
||||
[Groq](https://console.groq.com/docs/models),
|
||||
[Mistral](https://docs.mistral.ai/models/), and
|
||||
[Together](https://docs.together.ai/docs/inference/recommended-models), plus
|
||||
[OpenRouter's multimodal compatibility](https://openrouter.ai/docs/guides/overview/multimodal/overview)
|
||||
catalogs. Use `model_override` when a provider exposes a newer compatible model
|
||||
before the next node-pack release.
|
||||
|
||||
The capability routing follows the current official
|
||||
[OpenAI web-search](https://developers.openai.com/api/docs/guides/tools-web-search)
|
||||
and [structured-output](https://developers.openai.com/api/docs/guides/structured-outputs)
|
||||
contracts,
|
||||
[Gemini grounding](https://ai.google.dev/gemini-api/docs/google-search) and
|
||||
[structured output](https://ai.google.dev/gemini-api/docs/structured-output),
|
||||
[Claude web-search](https://platform.claude.com/docs/en/agents-and-tools/tool-use/web-search-tool)
|
||||
and [structured-output](https://platform.claude.com/docs/en/build-with-claude/structured-outputs)
|
||||
contracts, [xAI web search](https://docs.x.ai/developers/tools/web-search) and
|
||||
[structured outputs](https://docs.x.ai/developers/model-capabilities/text/structured-outputs),
|
||||
and [OpenRouter server-side search](https://openrouter.ai/docs/guides/features/server-tools/web-search).
|
||||
The local dialect is based on the
|
||||
[llama.cpp server API](https://github.com/ggml-org/llama.cpp/blob/master/tools/server/README.md).
|
||||
|
||||
API keys are not node inputs. A workflow contains only the provider selection,
|
||||
and the server resolves that provider's fixed environment variable at execution
|
||||
time. Built-in credentials are pinned to the provider's official HTTPS host;
|
||||
only the custom profile accepts a URL, and it can read only `CUSTOM_API_KEY`.
|
||||
Remote custom URLs require HTTPS, while keyless HTTP is restricted to
|
||||
`localhost`/loopback. Redirect following and environment proxies are disabled
|
||||
by default, API calls are stateless, OpenAI Responses explicitly use
|
||||
`store=false`, and provider exceptions are redacted before ComfyUI receives
|
||||
them.
|
||||
|
||||
Web search sends the prompt (and, where supported, the same multimodal request)
|
||||
to the selected provider's server-side search system. Do not enable it for
|
||||
content that must not be processed under that provider's search terms.
|
||||
|
||||
Opening an older `PromptGenerateAPI` workflow automatically clears its former
|
||||
plaintext key widget before the graph is configured. Save the migrated workflow
|
||||
to overwrite the old file, and rotate any key that was previously saved or
|
||||
shared. See [SECURITY.md](SECURITY.md) for setup and the exact threat model.
|
||||
|
||||
## Reliability guarantees
|
||||
|
||||
- Importing the pack performs no network access, compilation, or package install.
|
||||
- Missing optional backends fail only the node that needs them, with an
|
||||
actionable error.
|
||||
- Image inputs use ComfyUI `BHWC` batches; text responses preserve every batch
|
||||
item. Florence/PaLI masks use `BHW`.
|
||||
- `forceInput` string hacks were removed, preventing frontend widget-index drift.
|
||||
- Downloads stay inside the configured ComfyUI model directory.
|
||||
- CI installs and imports the full pack on Linux Python 3.10/3.13, Windows
|
||||
Python 3.12, and macOS Python 3.12. Backend contracts for CUDA, ROCm, Metal,
|
||||
XPU, and CPU are exercised without pretending hosted CPU runners are GPUs.
|
||||
|
||||
Run local checks with:
|
||||
|
||||
```bash
|
||||
PYTHONPATH=/path/to:/path/to/ComfyUI python -m pytest -q
|
||||
```
|
||||
|
||||
Real-weight checks are opt-in because they download multi-gigabyte checkpoints:
|
||||
|
||||
```bash
|
||||
python tests/manual_model_smoke.py --model "Qwen 3 VL 4B Instruct"
|
||||
python tests/manual_specialized_smoke.py --backend florence-large
|
||||
python tests/manual_llama_cpp_smoke.py --download
|
||||
```
|
||||
|
||||
See [MODEL_VALIDATION.md](MODEL_VALIDATION.md) for the exact real-weight and
|
||||
catalog-only evidence matrix.
|
||||
|
||||
Please report reproducible bugs at the
|
||||
[issue tracker](https://github.com/gokayfem/ComfyUI_VLM_nodes/issues).
|
||||
|
||||
<details>
|
||||
<summary><strong>Cite this project</strong></summary>
|
||||
|
||||
If ComfyUI VLM Nodes supports your work, please cite the software. GitHub also
|
||||
provides ready-to-copy APA and BibTeX entries via **Cite this repository**.
|
||||
|
||||
```bibtex
|
||||
@software{Aydogan_ComfyUI_VLM_Nodes_2026,
|
||||
author = {Aydoğan, Gökay},
|
||||
title = {ComfyUI VLM Nodes},
|
||||
version = {3.5.0},
|
||||
year = {2026},
|
||||
url = {https://github.com/gokayfem/ComfyUI_VLM_nodes}
|
||||
}
|
||||
```
|
||||
|
||||
[ORCID](https://orcid.org/0000-0002-2343-9433) · [Citation metadata](CITATION.cff)
|
||||
|
||||
</details>
|
||||
|
||||
+120
@@ -0,0 +1,120 @@
|
||||
# API credential security
|
||||
|
||||
## Guarantees
|
||||
|
||||
- API keys are never accepted as node inputs, widget values, workflow fields,
|
||||
outputs, metadata, or log messages.
|
||||
- Each built-in provider reads only its standard server-side environment
|
||||
variable and sends it only to that provider's fixed official HTTPS endpoint.
|
||||
- A built-in provider key cannot be combined with a workflow-supplied URL.
|
||||
- The custom endpoint reads only `CUSTOM_API_KEY`. Remote custom endpoints must
|
||||
use HTTPS; unencrypted and keyless requests are limited to loopback.
|
||||
- HTTP redirects and environment proxies are disabled by default. Proxy use is
|
||||
an explicit non-secret node option for installations that require it.
|
||||
- Hosted calls are stateless. No Python node-instance conversation history is
|
||||
retained, and OpenAI Responses requests set `store=false`.
|
||||
- Exceptions are bounded and redact the resolved key, URL-encoded variants,
|
||||
bearer tokens, common provider-key formats, authorization fields, and URL
|
||||
user-info before the message reaches ComfyUI.
|
||||
- Local image/video-frame uploads are uniformly sampled, resized,
|
||||
JPEG-compressed, limited to 4 MiB per image, and limited to 24 MiB total.
|
||||
- User JSON Schemas are size/depth/node bounded and may contain only local
|
||||
fragment `$ref` values. Remote URLs and file references are rejected before
|
||||
validation, preventing schema resolution from becoming an SSRF or local-file
|
||||
access path.
|
||||
|
||||
## Configure credentials
|
||||
|
||||
Set the matching variable in the environment that launches ComfyUI, then
|
||||
restart ComfyUI:
|
||||
|
||||
| Provider | Variable |
|
||||
| --- | --- |
|
||||
| OpenAI | `OPENAI_API_KEY` |
|
||||
| Google Gemini | `GEMINI_API_KEY` |
|
||||
| Anthropic | `ANTHROPIC_API_KEY` |
|
||||
| xAI | `XAI_API_KEY` |
|
||||
| DeepSeek | `DEEPSEEK_API_KEY` |
|
||||
| Groq | `GROQ_API_KEY` |
|
||||
| Mistral | `MISTRAL_API_KEY` |
|
||||
| Together AI | `TOGETHER_API_KEY` |
|
||||
| OpenRouter | `OPENROUTER_API_KEY` |
|
||||
| MiniMax | `MINIMAX_API_KEY` |
|
||||
| Custom remote endpoint | `CUSTOM_API_KEY` |
|
||||
| Universal VLA policy server | `VLA_POLICY_TOKEN` |
|
||||
| openpi WebSocket server | `OPENPI_API_KEY` |
|
||||
| Isaac-GR00T ZMQ server | `GROOT_API_TOKEN` |
|
||||
|
||||
For an interactive POSIX/WSL session, this avoids putting the value in shell
|
||||
history:
|
||||
|
||||
```bash
|
||||
read -rsp "Provider API key: " OPENAI_API_KEY
|
||||
export OPENAI_API_KEY
|
||||
python main.py
|
||||
```
|
||||
|
||||
Use the equivalent secret manager or service environment mechanism for a
|
||||
persistent installation. Do not commit a `.env` file, workflow containing an
|
||||
old key, shell script containing a key, or copied ComfyUI log.
|
||||
|
||||
Web search is disabled by default. Enabling it sends the request content to the
|
||||
selected provider's server-side search system and may have separate retention,
|
||||
regional-availability, and billing terms. Treat it as an explicit data-sharing
|
||||
choice; do not enable it for content that is outside those terms.
|
||||
|
||||
## Robotics policy endpoints
|
||||
|
||||
Robotics tokens are also server-side only. Workflow nodes select an endpoint,
|
||||
but cannot select an arbitrary environment variable or contain the secret
|
||||
value.
|
||||
|
||||
- The universal policy client permits unencrypted HTTP only on loopback.
|
||||
Remote use requires HTTPS plus `allow_remote=true`; redirects and
|
||||
environment proxies are disabled.
|
||||
- The openpi client permits unencrypted WebSocket only on loopback. Remote use
|
||||
requires WSS plus `allow_remote=true`.
|
||||
- GR00T's official ZeroMQ protocol has token authentication but no built-in
|
||||
transport encryption. Keep it on loopback/private infrastructure or place it
|
||||
inside an authenticated encrypted tunnel. Never expose its port directly to
|
||||
the public internet.
|
||||
- Camera payloads are JPEG-compressed and bounded per frame and per request.
|
||||
Response sizes, camera count, observation history, state/action dimensions,
|
||||
and action horizons are bounded before use.
|
||||
- MessagePack ndarray decoders reject object/void dtypes and never deserialize
|
||||
pickle. The included HTTP sidecar uses bounded JSON instead of LeRobot's
|
||||
pickle-based asynchronous transport.
|
||||
- Errors redact the resolved token and authorization-like values. Reports
|
||||
include only endpoint scheme/host/port, not request headers, full camera
|
||||
payloads, or state data.
|
||||
|
||||
Robot observations may expose people, homes, workplaces, proprietary tasks,
|
||||
and physical state. Treat them as sensitive even when no API key is present.
|
||||
The safety node is a data validation gate, not a certified control system.
|
||||
This package intentionally contains no ROS, serial, CAN, motor, or robot SDK
|
||||
transport; a separate controller must enforce emergency stop, deadman,
|
||||
watchdog, collision/workspace, command-age, and manufacturer limits.
|
||||
|
||||
## Legacy workflows
|
||||
|
||||
Versions before this security update exposed an `api_key` text widget.
|
||||
The frontend migration clears position 3 of every serialized
|
||||
`PromptGenerateAPI` node before LiteGraph creates the active node, including
|
||||
nodes inside saved subgraph definitions. The backend independently rejects any
|
||||
value that is not one of the two safe credential-source choices.
|
||||
|
||||
The source workflow file is not rewritten merely by opening it. Save the
|
||||
migrated workflow, securely remove old copies, and rotate any credential that
|
||||
was ever saved, shared, committed, backed up, or placed in an exported PNG.
|
||||
|
||||
## Threat boundary
|
||||
|
||||
ComfyUI custom nodes execute Python code with the permissions of the ComfyUI
|
||||
process. Another untrusted custom-node package can read the same process
|
||||
environment regardless of protections in this repository. Install only trusted
|
||||
node packs, keep ComfyUI authenticated and bound to a trusted interface, and do
|
||||
not expose an unauthenticated server to the public internet.
|
||||
|
||||
If a key may have been exposed, revoke it with the provider immediately, review
|
||||
usage, create a replacement with the minimum needed project permissions and
|
||||
spend limit, and restart ComfyUI with the replacement.
|
||||
+53
-42
@@ -1,56 +1,67 @@
|
||||
import importlib.util
|
||||
import os
|
||||
import importlib
|
||||
import pkg_resources
|
||||
import sys
|
||||
import subprocess
|
||||
import logging
|
||||
|
||||
# Define the check_requirements_installed function here or import it
|
||||
def check_requirements_installed(requirements_path):
|
||||
with open(requirements_path, 'r') as f:
|
||||
requirements = [pkg_resources.Requirement.parse(line.strip()) for line in f if line.strip()]
|
||||
from .nodes.runtime import register_model_folder
|
||||
|
||||
installed_packages = {pkg.key: pkg for pkg in pkg_resources.working_set}
|
||||
missing_packages = []
|
||||
for requirement in requirements:
|
||||
if requirement.key not in installed_packages or not installed_packages[requirement.key] in requirement:
|
||||
missing_packages.append(str(requirement))
|
||||
|
||||
if missing_packages:
|
||||
print(f"Missing or outdated packages: {', '.join(missing_packages)}")
|
||||
print("Installing/Updating missing packages...")
|
||||
subprocess.check_call([sys.executable, '-s', '-m', 'pip', 'install', *missing_packages])
|
||||
else:
|
||||
print("All packages from requirements.txt are installed and up to date.")
|
||||
requirements_path = os.path.join(os.path.dirname(os.path.realpath(__file__)), "requirements.txt")
|
||||
check_requirements_installed(requirements_path)
|
||||
|
||||
from .install_init import init, get_system_info, install_llama, install_autogptq
|
||||
system_info = get_system_info()
|
||||
install_llama(system_info)
|
||||
llama_cpp_agent_path = os.path.join(os.path.dirname(os.path.realpath(__file__)), "cpp_agent_req.txt")
|
||||
check_requirements_installed(llama_cpp_agent_path)
|
||||
install_autogptq(system_info)
|
||||
init()
|
||||
LOGGER = logging.getLogger("ComfyUI_VLM_nodes")
|
||||
register_model_folder()
|
||||
|
||||
node_list = [
|
||||
"moondream_script",
|
||||
"simpletext",
|
||||
"llavaloader",
|
||||
"suggest",
|
||||
"acceleration",
|
||||
"audioldm2",
|
||||
"diagnostics",
|
||||
"florence2",
|
||||
"grounding",
|
||||
"hosted_api",
|
||||
"joytag",
|
||||
"internlm",
|
||||
"kosmos2",
|
||||
"llavaloader",
|
||||
"mcllava",
|
||||
"minicpm",
|
||||
"minimax_music",
|
||||
"modern_vlm",
|
||||
"molmo",
|
||||
"moondream31",
|
||||
"moondream2",
|
||||
"moondream_script",
|
||||
"paligemma",
|
||||
"playmusic",
|
||||
"qwen2vl",
|
||||
"robotics",
|
||||
"sam2",
|
||||
"sam3_adapter",
|
||||
"simpletext",
|
||||
"spatial_parser",
|
||||
"suggest",
|
||||
"tracking",
|
||||
"uform",
|
||||
"video_intelligence",
|
||||
"vision_utils",
|
||||
]
|
||||
|
||||
NODE_CLASS_MAPPINGS = {}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {}
|
||||
IMPORT_ERRORS = {}
|
||||
|
||||
for module_name in node_list:
|
||||
imported_module = importlib.import_module(f".nodes.{module_name}", __name__)
|
||||
|
||||
NODE_CLASS_MAPPINGS = {**NODE_CLASS_MAPPINGS, **imported_module.NODE_CLASS_MAPPINGS}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {**NODE_DISPLAY_NAME_MAPPINGS, **imported_module.NODE_DISPLAY_NAME_MAPPINGS}
|
||||
try:
|
||||
imported_module = importlib.import_module(f".nodes.{module_name}", __name__)
|
||||
except Exception as exc:
|
||||
# A broken optional model must never prevent unrelated nodes from loading.
|
||||
IMPORT_ERRORS[module_name] = f"{type(exc).__name__}: {exc}"
|
||||
LOGGER.exception("Could not load optional node module %s", module_name)
|
||||
continue
|
||||
NODE_CLASS_MAPPINGS.update(
|
||||
getattr(imported_module, "NODE_CLASS_MAPPINGS", {})
|
||||
)
|
||||
NODE_DISPLAY_NAME_MAPPINGS.update(
|
||||
getattr(imported_module, "NODE_DISPLAY_NAME_MAPPINGS", {})
|
||||
)
|
||||
|
||||
|
||||
__all__ = ["NODE_CLASS_MAPPINGS", "NODE_DISPLAY_NAME_MAPPINGS"]
|
||||
|
||||
WEB_DIRECTORY = "./web"
|
||||
__all__ = [
|
||||
"NODE_CLASS_MAPPINGS",
|
||||
"NODE_DISPLAY_NAME_MAPPINGS",
|
||||
"WEB_DIRECTORY",
|
||||
]
|
||||
|
||||
@@ -0,0 +1,135 @@
|
||||
# Qwen3-VL cold-start research
|
||||
|
||||
This note separates weight loading from warm inference. The current promoted
|
||||
runtime remains SGLang 0.5.10 native + Triton multimodal attention + compiled
|
||||
decode at 190.5 ms end to end. FlashPack does not make a resident model decode
|
||||
faster; it targets the much larger cold-start path.
|
||||
|
||||
## Local profile
|
||||
|
||||
Host: RTX 3090 24 GB, WSL2 ext4, one 4,255,140,312-byte
|
||||
`Qwen/Qwen3-VL-2B-Instruct` safetensors checkpoint. Each cold sample ran in a
|
||||
fresh process after `POSIX_FADV_DONTNEED` was applied only to the measured file.
|
||||
Conversion to FlashPack was excluded. Three tensors spanning the packed file
|
||||
were checked bit-for-bit against safetensors and all passed.
|
||||
|
||||
| Loader | Reader staging | Cold seconds | Cold p50 / p95 | Effective p50 | Warm p50 | Result |
|
||||
| --- | --- | ---: | ---: | ---: | ---: | --- |
|
||||
| safetensors | library default | 58.55, 59.31, 60.18 | 59.31 / 60.18 s | 0.574 Gbit/s | 1.058 s | control |
|
||||
| safetensors fast GPU | library default | 62.31, 58.51, 60.63 | 60.63 / 62.31 s | 0.561 Gbit/s | 1.137 s | slower |
|
||||
| FlashPack direct I/O | 4 readers x 2 buffers x 32 MiB = 256 MiB | 44.78, 38.82, 43.74 | **43.74 / 44.78 s** | **0.779 Gbit/s** | not applicable to direct I/O | **26.3% faster** |
|
||||
| FlashPack direct I/O | 8 readers x 2 buffers x 16 MiB = 256 MiB | 45.74 (probe) | — | 0.744 Gbit/s | — | no improvement |
|
||||
| FlashPack buffered legacy | bounded internal buffer | 87.24 (probe) | — | 0.390 Gbit/s | 1.00 s | cold regression |
|
||||
|
||||
The upstream FlashPack default at the audited `a923a6c` revision attempted
|
||||
16 readers x 2 buffers x 64 MiB, a 2 GiB pinned staging pool, and failed with a
|
||||
CUDA pinned-allocation out-of-memory error on this host. The local profiler
|
||||
therefore defaults to the measured 256 MiB configuration. Production code
|
||||
must budget pinned memory from available host and GPU pressure rather than
|
||||
assuming that the upstream default is safe.
|
||||
|
||||
These are local storage results, not fal `/data` results. The approximately
|
||||
56x gap between cold safetensors (59.31 s) and warm safetensors (1.06 s) shows
|
||||
that this WSL profile is storage-bound. fal documents up to 25 Gbit/s for
|
||||
FlashPack on its infrastructure, but that number must not be presented as this
|
||||
model's measured startup speed until the same profiler runs inside the target
|
||||
fal machine.
|
||||
|
||||
## What FlashPack and ComfyUI contribute
|
||||
|
||||
FlashPack flattens a state dictionary into large dtype-grouped blocks, reads
|
||||
chunks in parallel, overlaps host reads with CUDA copies, and creates parameter
|
||||
views without a second GPU allocation. fal's persistent `/data` cache makes the
|
||||
packed file reusable across runners and deployments.
|
||||
|
||||
Current ComfyUI adds a complementary set of mechanisms:
|
||||
|
||||
- read-only safetensors memory maps annotated with exact file offsets;
|
||||
- direct file-slice-to-device reads where AIMDO is available;
|
||||
- bounded host buffers and asynchronous device copies otherwise;
|
||||
- pressure-aware pinned-memory registration and eviction;
|
||||
- model deduplication, residency, partial unload, and reuse;
|
||||
- module-ahead prefetch with stream synchronization;
|
||||
- two asynchronous offload streams by default on supported NVIDIA systems.
|
||||
|
||||
ComfyUI's dynamic-VRAM path is primarily a memory-capacity and model-switching
|
||||
feature. For a 2B checkpoint that fits comfortably on a 24 GB GPU, eagerly
|
||||
loading the complete pack once and retaining the SGLang process minimizes first
|
||||
request latency. Lazy layer materialization should be an explicit low-VRAM or
|
||||
multi-model mode, not the fast default.
|
||||
|
||||
## Proposed combined loader: FlashSlice
|
||||
|
||||
1. Convert the pinned checkpoint revision to one FlashPack file during image
|
||||
build or a one-time `/data` preparation job. Store its index, checksum,
|
||||
dtype, model revision, FlashPack revision, Torch version, and CUDA version.
|
||||
2. Instantiate the model with empty/meta parameters and map each parameter to
|
||||
the packed file's offset, borrowing ComfyUI's `TensorFileSlice` abstraction.
|
||||
3. For the latency path, eagerly stream the entire pack through a bounded pool.
|
||||
Start with a 256 MiB budget, four read workers, two buffers per worker, and
|
||||
two CUDA copy streams; autotune against the target machine and checkpoint.
|
||||
4. Pipeline file read, host staging, H2D copy, parameter binding, and runtime
|
||||
initialization. Never allocate a second full GPU state dictionary.
|
||||
5. Keep the initialized SGLang engine resident and reuse it for every ComfyUI
|
||||
execution. Do not reconstruct the engine per graph run.
|
||||
6. For low-VRAM or rapid model switching, retain the file-offset map and enable
|
||||
ComfyUI-style layer-ahead prefetch, bounded pinning, and pressure-aware
|
||||
eviction. Record this as a distinct runtime because its first-request shape
|
||||
differs from the eager path.
|
||||
|
||||
```text
|
||||
/data packed checkpoint
|
||||
|
|
||||
v
|
||||
bounded parallel reads --> pinned ring --> 2 CUDA streams --> empty parameters
|
||||
| |
|
||||
+------ file offsets for optional lazy/prefetch mode -----+
|
||||
|
|
||||
v
|
||||
resident SGLang engine
|
||||
```
|
||||
|
||||
## End-to-end startup ladder
|
||||
|
||||
Every deployment benchmark should emit timestamps for these phases. A single
|
||||
"cold start" duration is not actionable.
|
||||
|
||||
| Mark | Phase | Optimization |
|
||||
| --- | --- | --- |
|
||||
| T0 | request accepted | client region, upload size, connection reuse |
|
||||
| T1 | runner allocated | fal `min_concurrency`, `keep_alive`, capacity |
|
||||
| T2 | imports complete | small image, pinned dependencies, lazy imports |
|
||||
| T3 | checkpoint available | persistent `/data`, checksum hit, no download |
|
||||
| T4 | model skeleton ready | empty/meta initialization |
|
||||
| T5 | weights resident | bounded FlashPack/FlashSlice pipeline |
|
||||
| T6 | kernels ready | synchronized Inductor cache, GPU/version key |
|
||||
| T7 | serving ready | in-process engine or explicit readiness barrier |
|
||||
| T8 | first token | preprocessed fixed shape, CUDA graph/compile cache |
|
||||
| T9 | final token | existing SGLang steady-state benchmark |
|
||||
|
||||
Recommended production sequence:
|
||||
|
||||
1. Measure a true zero-runner fal cold start and a `/data`-cached cold start.
|
||||
2. Add the bounded packed loader; accept it only with exact tensor and output
|
||||
gates.
|
||||
3. Persist the compiled Inductor cache and warm the real 448-edge, batch-one
|
||||
image/decode shape during setup.
|
||||
4. Reuse the model process. For latency-critical traffic, compare
|
||||
`min_concurrency=1` against cost; for sporadic traffic, start with a longer
|
||||
`keep_alive` such as 300 seconds and measure the hit rate.
|
||||
5. Stream output so perceived latency follows TTFT, resize media before upload,
|
||||
and avoid base64 copies when a region-local URL is available.
|
||||
|
||||
## Primary sources
|
||||
|
||||
- [fal FlashPack optimization](https://fal.ai/docs/documentation/serverless/optimizations/flashpack)
|
||||
- [fal cold-start phases](https://fal.ai/docs/documentation/serverless/optimizations/optimize-cold-starts)
|
||||
- [fal compiled-cache synchronization](https://fal.ai/docs/documentation/serverless/optimizations/optimize-startup-with-compiled-caches)
|
||||
- [fal cold-start scaling controls](https://fal.ai/docs/documentation/serverless/optimizations/cold-start-scaling)
|
||||
- [fal parallel file loading](https://fal.ai/docs/documentation/serverless/optimizations/parallel-file-loading)
|
||||
- [FlashPack source](https://github.com/fal-ai/flashpack)
|
||||
- [ComfyUI tensor loading and mmap metadata](https://github.com/Comfy-Org/ComfyUI/blob/master/comfy/utils.py)
|
||||
- [ComfyUI model residency and loading](https://github.com/Comfy-Org/ComfyUI/blob/master/comfy/model_management.py)
|
||||
- [ComfyUI file-slice-to-device pipeline](https://github.com/Comfy-Org/ComfyUI/blob/master/comfy/memory_management.py)
|
||||
- [ComfyUI module prefetch](https://github.com/Comfy-Org/ComfyUI/blob/master/comfy/model_prefetch.py)
|
||||
- [ComfyUI bounded pinned memory](https://github.com/Comfy-Org/ComfyUI/blob/master/comfy/pinned_memory.py)
|
||||
@@ -0,0 +1,196 @@
|
||||
# VLM Speed Lab
|
||||
|
||||
This directory turns performance work into a sequence of reproducible,
|
||||
quality-gated experiments. The first target is the repository default:
|
||||
`Qwen/Qwen3-VL-2B-Instruct`.
|
||||
|
||||
## Rule zero
|
||||
|
||||
A result is a speedup only when it uses the same checkpoint revision, media,
|
||||
prompts, seed, precision policy, and decoding settings as its baseline, and its
|
||||
task-quality score remains inside the declared tolerance. A faster result that
|
||||
misses the quality gate is recorded as a regression.
|
||||
|
||||
## Iteration order
|
||||
|
||||
1. Transformers BF16 + SDPA baseline.
|
||||
2. Existing adaptive sampling and pixel-budget nodes.
|
||||
3. Flash Attention 2.
|
||||
4. `torch.compile` / CUDA graph experiments.
|
||||
5. SGLang with its declared attention backend (including FlashInfer where
|
||||
selected by the runtime).
|
||||
6. TensorRT component engines where the model is exportable; TensorRT-LLM only
|
||||
where the upstream runtime supports the complete architecture.
|
||||
|
||||
Change one performance variable at a time. Run single-request latency first,
|
||||
then concurrency sweeps. Never mix cold-start and steady-state samples.
|
||||
|
||||
## Reproduce the first RTX 3090 matrix in WSL
|
||||
|
||||
The committed `qwen3-vl-2b-matrix-tf5-rubric.json` artifact was generated on
|
||||
Ubuntu 22.04 under WSL2 with an RTX 3090, PyTorch 2.8.0+cu128, and Transformers
|
||||
5.12.1. Model files, the virtual environment, media, and results all lived on
|
||||
the WSL ext4 disk rather than a `/mnt/c` or `/mnt/d` mount.
|
||||
|
||||
```bash
|
||||
HF_ENABLE_PARALLEL_LOADING=true \
|
||||
HF_PARALLEL_LOADING_WORKERS=8 \
|
||||
./.venv-bench/bin/python benchmarks/qwen3_vl_matrix.py \
|
||||
--image benchmarks/media/qwen-demo.jpeg \
|
||||
--runs 10 \
|
||||
--max-new-tokens 96 \
|
||||
--output benchmarks/results/qwen3-vl-2b-matrix-tf5-rubric.json
|
||||
```
|
||||
|
||||
Ten measured runs follow two warmups for dynamic-cache variants and six for
|
||||
the compiled static-cache variant. The one-time compilation sample remains in
|
||||
`warmup_samples`; it is never mixed into steady-state percentiles.
|
||||
|
||||
| Iteration | Input | TTFT p50 | E2E p50 | Output tok/s | Peak VRAM | Quality |
|
||||
| --- | ---: | ---: | ---: | ---: | ---: | --- |
|
||||
| 00 SDPA + dynamic | 2048x1365 | 700.3 ms | 1395.7 ms | 42.3 | 4.55 GiB | rubric pass |
|
||||
| 01a SDPA + dynamic | 672x448 | 112.8 ms | 844.0 ms | 42.2 | 4.04 GiB | rubric pass |
|
||||
| 01b SDPA + dynamic | 448x299 | 88.2 ms | 774.1 ms | 43.7 | 4.00 GiB | rubric pass |
|
||||
| 02 SDPA + static compiled | 448x299 | 76.6 ms | 290.1 ms | 139.4 | 4.02 GiB | rubric + exact-output pass vs 01b |
|
||||
| 03a FA2 + dynamic | 448x299 | 106.6 ms | 1033.3 ms | 32.3 | 4.00 GiB | exact pass; performance regression |
|
||||
| 03b FA2 + static compiled | 448x299 | 265.0 ms | 3028.0 ms | 34.4 | 4.02 GiB | **fail; corrupted repetitive output** |
|
||||
| 04 SDPA + static + scoped TF32 | 448x299 | 74.3 ms | 274.5 ms | 149.2 | 4.03 GiB | rubric + exact-output pass vs 01b |
|
||||
|
||||
Iteration 04 is 9.43x faster to first token, 5.08x faster end to end, and
|
||||
3.53x higher output throughput than iteration 00. Resizing preserves the task
|
||||
rubric but is not byte-identical to source-resolution output; the artifact
|
||||
records both facts. The cache/compiler change is byte-identical to iteration
|
||||
01b, as is scoped TF32. Flash Attention 2 is retained as negative evidence:
|
||||
its dynamic-cache run was correct but slower, while its static-cache pairing
|
||||
failed the exact-output gate. These are single-image, batch-one latency
|
||||
results—not yet a general VLM quality claim.
|
||||
|
||||
Parallel safetensor loading reduced warm-filesystem model/processor setup from
|
||||
88.351 seconds to 6.858 seconds. Treat this as a warm-cache startup result;
|
||||
network download time is outside the measurement.
|
||||
|
||||
The separate [cold-start study](COLD_START_RESEARCH.md) profiles the same
|
||||
checkpoint from disk to GPU and combines a bounded FlashPack reader with
|
||||
ComfyUI's file-slice, pinned-memory, residency, and prefetch ideas. On the local
|
||||
WSL host, the validated bounded FlashPack configuration reduced cold weight
|
||||
loading from 59.31 seconds to 43.74 seconds p50 (26.3%). This is explicitly a
|
||||
local storage result; fal `/data` remains to be measured independently.
|
||||
|
||||
## SGLang and FlashInfer matrix
|
||||
|
||||
The same 448x299 image, prompt, greedy decode, 96-token cap, RTX 3090, three
|
||||
warmups, and ten measured requests were used for the serving-runtime matrix.
|
||||
SGLang 0.5.10.post1 ran with PyTorch 2.9.1+cu128, Transformers 5.3.0, and
|
||||
FlashInfer 0.6.7.post3. The concept gate requires the woman, golden retriever,
|
||||
beach, and high-five action; inflection aliases such as `high-fiving` are
|
||||
accepted within that action concept.
|
||||
|
||||
| Iteration | Runtime change | TTFT p50 / p95 | E2E p50 / p95 | Output tok/s | Quality |
|
||||
| --- | --- | ---: | ---: | ---: | --- |
|
||||
| 05a SGLang 0.5.9 native | FlashInfer + SDPA vision | 38.3 / 42.9 ms | 43.3 / 48.0 ms | 393.9 | **fail; output was only a code fence** |
|
||||
| 05b SGLang 0.5.10 Transformers backend | Version + model implementation | 75.6 / 79.2 ms | 254.2 / 257.5 ms | 173.5 | pass; exact vs 01b |
|
||||
| 05c SGLang 0.5.10 native | Native model implementation | 35.2 / 38.3 ms | 240.6 / 243.6 ms | 194.7 | concept pass |
|
||||
| 05d Triton multimodal attention | SDPA vision -> Triton vision | 35.5 / 37.9 ms | 193.6 / 195.3 ms | 196.4 | pass; exact vs 01b |
|
||||
| 05e compiled decode | `torch.compile`, max batch 4 | 37.5 / 41.0 ms | 190.5 / 194.7 ms | 202.6 | pass; exact vs 01b |
|
||||
|
||||
Iteration 05e is 7.33x faster end to end and delivers 4.79x higher output
|
||||
throughput than iteration 00. Iteration 05c retains the best TTFT at 19.88x
|
||||
faster than iteration 00, while 05e trades 2.2 ms of TTFT for the best E2E and
|
||||
decode throughput. The one-request 0.5.10 cold probe took 17.6 seconds because
|
||||
of one-time compilation and is kept separate from steady-state percentiles.
|
||||
|
||||
The 0.5.9 result demonstrates why latency cannot be promoted without output
|
||||
evidence: its apparently extraordinary timing came from terminating after two
|
||||
invalid tokens. The 0.5.10 release fixed the native vision path for this case.
|
||||
The current 0.5.15.post1 release was also installed and audited, but its CUDA
|
||||
13 / PyTorch 2.11 build cannot initialize CUDA on the machine's NVIDIA 560.94
|
||||
driver, so it is recorded as incompatible rather than benchmarked.
|
||||
|
||||
## TensorRT vision engine
|
||||
|
||||
Current TensorRT-LLM does not list Qwen3-VL as a supported multimodal serving
|
||||
architecture, so iteration 06 does not mislabel its PyTorch backend as a
|
||||
TensorRT engine. Instead, Torch-TensorRT 2.9.0 and TensorRT 10.13.3 compile the
|
||||
fixed-shape Qwen3-VL vision tower into one real BF16 engine on the RTX 3090.
|
||||
The graph has zero PyTorch fallback partitions.
|
||||
|
||||
```bash
|
||||
./.venv-tensorrt/bin/python benchmarks/qwen3_vl_tensorrt.py \
|
||||
--image benchmarks/media/qwen-demo.jpeg \
|
||||
--longest-edge 448 \
|
||||
--warmups 3 \
|
||||
--runs 10 \
|
||||
--generation-warmups 1 \
|
||||
--generation-runs 3 \
|
||||
--output benchmarks/results/qwen3-vl-2b-tensorrt-vision-full.json
|
||||
```
|
||||
|
||||
| Path | Vision p50 | TTFT p50 / p95 | E2E p50 / p95 | Output tok/s | Quality |
|
||||
| --- | ---: | ---: | ---: | ---: | --- |
|
||||
| Torch 2.9 eager control | 2385.3 ms | 2452.9 / 2464.3 ms | 2660.6 / 2674.7 ms | 143.3 | 3/3 identical |
|
||||
| TensorRT vision + unchanged decoder | 9.1 ms | 61.4 / 62.4 ms | 273.4 / 274.0 ms | 142.1 | exact output vs eager |
|
||||
|
||||
Engine construction took 98.070 seconds and is reported separately from
|
||||
inference. TensorRT produced the same 31-token sentence in every full-model
|
||||
sample. Its isolated 262.8x vision speedup is real relative to the Torch 2.9
|
||||
eager control but is not the cross-stack headline: the established Torch 2.8
|
||||
Transformers path already runs end to end in 274.5 ms, and SGLang iteration
|
||||
05e remains the overall winner at 190.5 ms. The useful result is a verified
|
||||
9.1 ms vision engine and a new 61.4 ms Transformers TTFT.
|
||||
|
||||
Iteration 07 serializes that engine and injects its packed pooler plus three
|
||||
deep-stack tensors into SGLang's native decoder. The static bridge only accepts
|
||||
the compiled `(1, 18, 28)` grid; other image shapes fall back to SGLang's
|
||||
unchanged vision path.
|
||||
|
||||
| Path | TTFT p50 / p95 | E2E p50 / p95 | Output tok/s | Semantic gate | Exact gate |
|
||||
| --- | ---: | ---: | ---: | --- | --- |
|
||||
| 05e SGLang control | 37.5 / 41.0 ms | **190.5 / 194.7 ms** | **202.6** | pass | pass; 31 tokens |
|
||||
| 07 TensorRT + SGLang | **34.9 / 37.8 ms** | 250.7 / 366.1 ms | 176.1 | pass | **fail; 40 tokens** |
|
||||
|
||||
The bridge reduced TTFT by 7.0%, but numerical differences in the Transformers
|
||||
vision engine changed greedy decoding to a longer, semantically correct
|
||||
caption. That makes iteration 07 a measured regression rather than a promoted
|
||||
speedup. The next experiment is to compile SGLang-native vision weights and
|
||||
preserve the exact 31-token output.
|
||||
|
||||
## Run the OpenAI-compatible benchmark
|
||||
|
||||
SGLang and TensorRT-LLM both expose OpenAI-compatible chat endpoints. Start
|
||||
one server, copy `suite.example.json`, point its cases to local benchmark media,
|
||||
and run:
|
||||
|
||||
```bash
|
||||
python benchmarks/vlm_bench.py \
|
||||
--suite benchmarks/suite.local.json \
|
||||
--base-url http://127.0.0.1:8000/v1 \
|
||||
--backend sglang \
|
||||
--label qwen3-vl-2b-sglang \
|
||||
--warmups 3 \
|
||||
--runs 30
|
||||
```
|
||||
|
||||
The runner writes one immutable JSON artifact under `benchmarks/results/`.
|
||||
It records raw model output, per-request latency and time-to-first-token,
|
||||
aggregate percentiles, quality scores, media hashes, server identity, and the
|
||||
local Git commit. Do not hand-edit result artifacts.
|
||||
|
||||
## Required suite fields
|
||||
|
||||
Each case declares a task and an evaluator:
|
||||
|
||||
- `keywords`: case-insensitive keyword recall for captions.
|
||||
- `concepts`: required semantic concepts, each with one or more accepted aliases.
|
||||
- `exact`: normalized exact match for OCR and constrained answers.
|
||||
- `number`: extracts the first integer for counting tasks.
|
||||
|
||||
Detection, segmentation, and tracking evaluators will be added after the first
|
||||
text-output baseline is frozen. Their artifacts will use the same run envelope
|
||||
and add box, mask, or track data rather than creating a separate leaderboard.
|
||||
|
||||
## Result review
|
||||
|
||||
The comparison site lives in `benchmarks/site`. It shows regressions alongside
|
||||
winners and never substitutes estimates for missing GPU runs.
|
||||
The existing `11.38×` figure is explicitly labeled as frame-by-pixel input-work
|
||||
reduction, not end-to-end model acceleration.
|
||||
@@ -0,0 +1 @@
|
||||
"""Reproducible performance benchmarks for ComfyUI VLM Nodes."""
|
||||
@@ -0,0 +1,11 @@
|
||||
# Benchmark media
|
||||
|
||||
`qwen-demo.jpeg` is the public demonstration image linked by the Qwen-VL
|
||||
project and used only as a reproducible benchmark input.
|
||||
|
||||
- Source: <https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-VL/assets/demo.jpeg>
|
||||
- Dimensions: 2048x1365
|
||||
- SHA-256: `9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2`
|
||||
|
||||
The image is not presented as repository-owned content. Keep its provenance
|
||||
with any redistributed benchmark artifact.
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 485 KiB |
@@ -0,0 +1,227 @@
|
||||
"""Profile cold and warm disk-to-GPU loading for Qwen3-VL weights.
|
||||
|
||||
FlashPack conversion is deliberately outside the timed path. Each measured
|
||||
run uses a new Python process so CUDA allocator state cannot leak across runs.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import gc
|
||||
import json
|
||||
import os
|
||||
import statistics
|
||||
import subprocess
|
||||
import sys
|
||||
import time
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
|
||||
def drop_file_cache(path: Path) -> None:
|
||||
"""Ask Linux to evict this file's pages without dropping global caches."""
|
||||
if not hasattr(os, "posix_fadvise"):
|
||||
return
|
||||
descriptor = os.open(path, os.O_RDONLY)
|
||||
try:
|
||||
os.posix_fadvise(descriptor, 0, 0, os.POSIX_FADV_DONTNEED)
|
||||
finally:
|
||||
os.close(descriptor)
|
||||
|
||||
|
||||
def load_once(method: str, path: Path) -> dict[str, Any]:
|
||||
import torch
|
||||
|
||||
torch.cuda.empty_cache()
|
||||
torch.cuda.reset_peak_memory_stats()
|
||||
started = time.perf_counter()
|
||||
if method.startswith("safetensors"):
|
||||
if method == "safetensors_fast_gpu":
|
||||
os.environ["SAFETENSORS_FAST_GPU"] = "1"
|
||||
else:
|
||||
os.environ.pop("SAFETENSORS_FAST_GPU", None)
|
||||
from safetensors.torch import load_file
|
||||
|
||||
loaded = load_file(str(path), device="cuda")
|
||||
tensor_count = len(loaded)
|
||||
elif method == "flashpack":
|
||||
# FlashPack main currently defaults to 16 readers, two 64 MiB pinned
|
||||
# buffers per reader (2 GiB total). That failed on the RTX 3090 WSL
|
||||
# test host. Keep the benchmark's default bounded and let callers
|
||||
# override every value explicitly when tuning another machine.
|
||||
os.environ.setdefault("FLASHPACK_READ_THREADS", "4")
|
||||
os.environ.setdefault("FLASHPACK_READ_CHUNK_BYTES", str(32 * 1024 * 1024))
|
||||
os.environ.setdefault("FLASHPACK_CACHE_PINNED", "0")
|
||||
from flashpack.deserialization import read_flashpack_file
|
||||
|
||||
loaded, metadata = read_flashpack_file(path=str(path), device="cuda")
|
||||
tensor_count = len(metadata["index"])
|
||||
else:
|
||||
raise ValueError(f"Unknown method: {method}")
|
||||
torch.cuda.synchronize()
|
||||
elapsed = time.perf_counter() - started
|
||||
peak_bytes = torch.cuda.max_memory_allocated()
|
||||
del loaded
|
||||
gc.collect()
|
||||
torch.cuda.empty_cache()
|
||||
return {
|
||||
"seconds": elapsed,
|
||||
"tensor_count": tensor_count,
|
||||
"peak_gpu_bytes": peak_bytes,
|
||||
}
|
||||
|
||||
|
||||
def worker(method: str, path: Path, runs: int, cold_only: bool) -> None:
|
||||
samples = []
|
||||
for _ in range(runs):
|
||||
drop_file_cache(path)
|
||||
cold = load_once(method, path)
|
||||
warm = None if cold_only else load_once(method, path)
|
||||
samples.append({"method": method, "cold": cold, "warm": warm})
|
||||
print(json.dumps(samples[0] if runs == 1 else {"samples": samples}))
|
||||
|
||||
|
||||
def prepare(safetensors_path: Path, flashpack_path: Path) -> dict[str, Any]:
|
||||
import torch
|
||||
from flashpack import is_flashpack_file, pack_to_file
|
||||
from flashpack.deserialization import (
|
||||
iterate_from_flash_tensor,
|
||||
read_flashpack_file,
|
||||
)
|
||||
from safetensors import safe_open
|
||||
from safetensors.torch import load_file
|
||||
|
||||
conversion_seconds = 0.0
|
||||
if not flashpack_path.exists() or not is_flashpack_file(str(flashpack_path)):
|
||||
flashpack_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
started = time.perf_counter()
|
||||
state_dict = load_file(str(safetensors_path), device="cpu")
|
||||
pack_to_file(
|
||||
state_dict,
|
||||
str(flashpack_path),
|
||||
target_dtype=None,
|
||||
silent=False,
|
||||
)
|
||||
conversion_seconds = time.perf_counter() - started
|
||||
del state_dict
|
||||
gc.collect()
|
||||
|
||||
storage, metadata = read_flashpack_file(str(flashpack_path), device="cpu")
|
||||
packed_tensors = dict(iterate_from_flash_tensor(storage, metadata))
|
||||
names = list(packed_tensors)
|
||||
sample_names = [names[0], names[len(names) // 2], names[-1]]
|
||||
exact = {}
|
||||
with safe_open(str(safetensors_path), framework="pt", device="cpu") as source:
|
||||
for name in sample_names:
|
||||
exact[name] = bool(torch.equal(source.get_tensor(name), packed_tensors[name]))
|
||||
del packed_tensors, storage
|
||||
gc.collect()
|
||||
drop_file_cache(safetensors_path)
|
||||
drop_file_cache(flashpack_path)
|
||||
return {
|
||||
"conversion_seconds": conversion_seconds,
|
||||
"flashpack_bytes": flashpack_path.stat().st_size,
|
||||
"tensor_count": len(metadata["index"]),
|
||||
"sample_exact": exact,
|
||||
}
|
||||
|
||||
|
||||
def percentile(values: list[float], fraction: float) -> float:
|
||||
ordered = sorted(values)
|
||||
index = min(len(ordered) - 1, int(round((len(ordered) - 1) * fraction)))
|
||||
return ordered[index]
|
||||
|
||||
|
||||
def summarize(samples: list[dict[str, Any]], file_bytes: int) -> dict[str, Any]:
|
||||
summary = {}
|
||||
for cache_state in ("cold", "warm"):
|
||||
seconds = [sample[cache_state]["seconds"] for sample in samples]
|
||||
median = statistics.median(seconds)
|
||||
summary[cache_state] = {
|
||||
"seconds": seconds,
|
||||
"p50_seconds": median,
|
||||
"p95_seconds": percentile(seconds, 0.95),
|
||||
"p50_throughput_gbps": file_bytes * 8 / median / 1e9,
|
||||
"peak_gpu_bytes": max(
|
||||
sample[cache_state]["peak_gpu_bytes"] for sample in samples
|
||||
),
|
||||
}
|
||||
return summary
|
||||
|
||||
|
||||
def main() -> None:
|
||||
parser = argparse.ArgumentParser()
|
||||
parser.add_argument("--safetensors", type=Path, required=True)
|
||||
parser.add_argument("--flashpack", type=Path, required=True)
|
||||
parser.add_argument("--runs", type=int, default=3)
|
||||
parser.add_argument("--output", type=Path)
|
||||
parser.add_argument("--worker", choices=("safetensors", "safetensors_fast_gpu", "flashpack"))
|
||||
parser.add_argument("--worker-runs", type=int, default=1)
|
||||
parser.add_argument("--cold-only", action="store_true")
|
||||
args = parser.parse_args()
|
||||
|
||||
if args.worker:
|
||||
worker(
|
||||
args.worker,
|
||||
args.flashpack if args.worker == "flashpack" else args.safetensors,
|
||||
args.worker_runs,
|
||||
args.cold_only,
|
||||
)
|
||||
return
|
||||
|
||||
preparation = prepare(args.safetensors, args.flashpack)
|
||||
methods = ("safetensors", "safetensors_fast_gpu", "flashpack")
|
||||
result: dict[str, Any] = {
|
||||
"schema_version": 1,
|
||||
"checkpoint": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"safetensors_bytes": args.safetensors.stat().st_size,
|
||||
"flashpack_reader": {
|
||||
"threads": int(os.environ.get("FLASHPACK_READ_THREADS", "4")),
|
||||
"chunk_bytes": int(
|
||||
os.environ.get("FLASHPACK_READ_CHUNK_BYTES", str(32 * 1024 * 1024))
|
||||
),
|
||||
"cache_pinned": os.environ.get("FLASHPACK_CACHE_PINNED", "0"),
|
||||
},
|
||||
"preparation": preparation,
|
||||
"methods": {},
|
||||
}
|
||||
for method in methods:
|
||||
samples = []
|
||||
for _ in range(args.runs):
|
||||
completed = subprocess.run(
|
||||
[
|
||||
sys.executable,
|
||||
str(Path(__file__).resolve()),
|
||||
"--safetensors",
|
||||
str(args.safetensors),
|
||||
"--flashpack",
|
||||
str(args.flashpack),
|
||||
"--worker",
|
||||
method,
|
||||
],
|
||||
check=True,
|
||||
capture_output=True,
|
||||
text=True,
|
||||
)
|
||||
samples.append(json.loads(completed.stdout.strip().splitlines()[-1]))
|
||||
file_bytes = (
|
||||
preparation["flashpack_bytes"]
|
||||
if method == "flashpack"
|
||||
else args.safetensors.stat().st_size
|
||||
)
|
||||
result["methods"][method] = summarize(samples, file_bytes)
|
||||
if args.output:
|
||||
args.output.parent.mkdir(parents=True, exist_ok=True)
|
||||
args.output.write_text(
|
||||
json.dumps(result, indent=2) + "\n", encoding="utf-8"
|
||||
)
|
||||
|
||||
payload = json.dumps(result, indent=2)
|
||||
print(payload)
|
||||
if args.output:
|
||||
args.output.parent.mkdir(parents=True, exist_ok=True)
|
||||
args.output.write_text(payload + "\n", encoding="utf-8")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,213 @@
|
||||
"""Run the core Qwen3-VL optimization matrix in one loaded-model process."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import platform
|
||||
import time
|
||||
from datetime import UTC, datetime
|
||||
from pathlib import Path
|
||||
|
||||
import torch
|
||||
from PIL import Image
|
||||
from qwen3_vl_transformers import aggregate, resize_to_longest_edge, run_sample
|
||||
from transformers import AutoModelForImageTextToText, AutoProcessor
|
||||
|
||||
VARIANTS = (
|
||||
{
|
||||
"id": "00",
|
||||
"label": "BF16 SDPA / dynamic cache / source resolution",
|
||||
"longest_edge": None,
|
||||
"cache": "dynamic",
|
||||
"warmups": 2,
|
||||
},
|
||||
{
|
||||
"id": "01a",
|
||||
"label": "BF16 SDPA / dynamic cache / 672px edge",
|
||||
"longest_edge": 672,
|
||||
"cache": "dynamic",
|
||||
"warmups": 2,
|
||||
},
|
||||
{
|
||||
"id": "01b",
|
||||
"label": "BF16 SDPA / dynamic cache / 448px edge",
|
||||
"longest_edge": 448,
|
||||
"cache": "dynamic",
|
||||
"warmups": 2,
|
||||
},
|
||||
{
|
||||
"id": "02",
|
||||
"label": "BF16 SDPA / static compiled cache / 448px edge",
|
||||
"longest_edge": 448,
|
||||
"cache": "static",
|
||||
"warmups": 6,
|
||||
"exact_reference": "01b",
|
||||
},
|
||||
)
|
||||
|
||||
DEFAULT_CONCEPT_GROUPS = (
|
||||
("woman", "person"),
|
||||
("golden retriever", "dog"),
|
||||
("beach", "sand"),
|
||||
("high-five", "high five"),
|
||||
)
|
||||
|
||||
|
||||
def evaluate_concepts(output: str, groups: tuple[tuple[str, ...], ...]) -> dict:
|
||||
normalized = output.casefold()
|
||||
matched = [next((term for term in group if term in normalized), None) for group in groups]
|
||||
return {
|
||||
"passed": all(matched),
|
||||
"matched": matched,
|
||||
"required": [list(group) for group in groups],
|
||||
}
|
||||
|
||||
|
||||
def main() -> None:
|
||||
parser = argparse.ArgumentParser(description=__doc__)
|
||||
parser.add_argument("--image", type=Path, required=True)
|
||||
parser.add_argument("--model", default="Qwen/Qwen3-VL-2B-Instruct")
|
||||
parser.add_argument("--prompt", default="Describe this image precisely in one sentence.")
|
||||
parser.add_argument("--runs", type=int, default=10)
|
||||
parser.add_argument("--max-new-tokens", type=int, default=96)
|
||||
parser.add_argument(
|
||||
"--output",
|
||||
type=Path,
|
||||
default=Path("benchmarks/results/qwen3-vl-2b-matrix-tf5.json"),
|
||||
)
|
||||
args = parser.parse_args()
|
||||
source_image = Image.open(args.image).convert("RGB")
|
||||
|
||||
load_started = time.perf_counter()
|
||||
processor = AutoProcessor.from_pretrained(args.model)
|
||||
model = AutoModelForImageTextToText.from_pretrained(
|
||||
args.model,
|
||||
dtype=torch.bfloat16,
|
||||
attn_implementation="sdpa",
|
||||
device_map="cuda",
|
||||
).eval()
|
||||
torch.cuda.synchronize()
|
||||
load_seconds = time.perf_counter() - load_started
|
||||
|
||||
results = []
|
||||
output_hashes: dict[str, str] = {}
|
||||
baseline_hash: str | None = None
|
||||
baseline_summary = None
|
||||
for variant in VARIANTS:
|
||||
image = resize_to_longest_edge(source_image, variant["longest_edge"])
|
||||
warmup_samples = []
|
||||
measured_samples = []
|
||||
total = int(variant["warmups"]) + args.runs
|
||||
for index in range(total):
|
||||
sample = run_sample(
|
||||
model,
|
||||
processor,
|
||||
image,
|
||||
args.prompt,
|
||||
max_new_tokens=args.max_new_tokens,
|
||||
cache_implementation=str(variant["cache"]),
|
||||
min_pixels=None,
|
||||
max_pixels=None,
|
||||
disable_compile=False,
|
||||
)
|
||||
target = warmup_samples if index < int(variant["warmups"]) else measured_samples
|
||||
target.append(sample)
|
||||
print(
|
||||
f"{variant['id']} {index + 1}/{total} "
|
||||
f"ttft={sample['ttft_ms']:.1f}ms "
|
||||
f"e2e={sample['e2e_ms']:.1f}ms "
|
||||
f"tok/s={sample['output_tokens_per_second']}",
|
||||
flush=True,
|
||||
)
|
||||
summary = aggregate(measured_samples)
|
||||
if baseline_hash is None:
|
||||
baseline_hash = measured_samples[0]["output_sha256"]
|
||||
baseline_summary = summary
|
||||
output_hashes[str(variant["id"])] = measured_samples[0]["output_sha256"]
|
||||
rubric_results = [
|
||||
evaluate_concepts(sample["output"], DEFAULT_CONCEPT_GROUPS)
|
||||
for sample in measured_samples
|
||||
]
|
||||
exact_reference = variant.get("exact_reference")
|
||||
exact_hash = (
|
||||
output_hashes[str(exact_reference)] if exact_reference is not None else None
|
||||
)
|
||||
exact_passed = (
|
||||
all(sample["output_sha256"] == exact_hash for sample in measured_samples)
|
||||
if exact_hash is not None
|
||||
else None
|
||||
)
|
||||
rubric_passed = all(result["passed"] for result in rubric_results)
|
||||
speedup = {
|
||||
"ttft": round(
|
||||
baseline_summary["ttft_ms"]["p50"] / summary["ttft_ms"]["p50"], 3
|
||||
),
|
||||
"e2e": round(
|
||||
baseline_summary["e2e_ms"]["p50"] / summary["e2e_ms"]["p50"], 3
|
||||
),
|
||||
"throughput": round(
|
||||
summary["output_tokens_per_second_mean"]
|
||||
/ baseline_summary["output_tokens_per_second_mean"],
|
||||
3,
|
||||
),
|
||||
}
|
||||
results.append(
|
||||
{
|
||||
**variant,
|
||||
"processed_width": image.width,
|
||||
"processed_height": image.height,
|
||||
"quality_gate": {
|
||||
"method": "required visual concepts"
|
||||
+ (
|
||||
f" plus byte-identical output against variant {exact_reference}"
|
||||
if exact_reference is not None
|
||||
else ""
|
||||
),
|
||||
"passed": rubric_passed and exact_passed is not False,
|
||||
"concepts": rubric_results[0],
|
||||
"exact_output_reference": exact_reference,
|
||||
"exact_output_passed": exact_passed,
|
||||
"exact_output_vs_baseline": all(
|
||||
sample["output_sha256"] == baseline_hash
|
||||
for sample in measured_samples
|
||||
),
|
||||
},
|
||||
"speedup_vs_baseline": speedup,
|
||||
"summary": summary,
|
||||
"warmup_samples": warmup_samples,
|
||||
"samples": measured_samples,
|
||||
}
|
||||
)
|
||||
|
||||
artifact = {
|
||||
"schema": "comfyui-vlm/optimization-matrix",
|
||||
"version": 1,
|
||||
"created_at": datetime.now(UTC).isoformat(),
|
||||
"model": args.model,
|
||||
"media": {
|
||||
"path": str(args.image.resolve()),
|
||||
"source_width": source_image.width,
|
||||
"source_height": source_image.height,
|
||||
},
|
||||
"prompt": args.prompt,
|
||||
"model_load_seconds": round(load_seconds, 3),
|
||||
"environment": {
|
||||
"platform": platform.platform(),
|
||||
"python": platform.python_version(),
|
||||
"torch": torch.__version__,
|
||||
"cuda": torch.version.cuda,
|
||||
"gpu": torch.cuda.get_device_name(),
|
||||
"transformers": __import__("transformers").__version__,
|
||||
},
|
||||
"runs_per_variant": args.runs,
|
||||
"variants": results,
|
||||
}
|
||||
args.output.parent.mkdir(parents=True, exist_ok=True)
|
||||
args.output.write_text(json.dumps(artifact, indent=2) + "\n", encoding="utf-8")
|
||||
print(json.dumps([{v["id"]: v["summary"]} for v in results], indent=2))
|
||||
print(args.output)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,113 @@
|
||||
"""Inject a serialized TensorRT Qwen3-VL vision engine into SGLang.
|
||||
|
||||
The bridge is deliberately static-shape and quality-safe. Requests matching the
|
||||
compiled 448px benchmark grid use TensorRT; every other shape takes SGLang's
|
||||
unchanged native vision path.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import logging
|
||||
import os
|
||||
import time
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
|
||||
LOGGER = logging.getLogger("sglang.tensorrt_bridge")
|
||||
ENGINE_ENV = "QWEN3_VL_TRT_ENGINE"
|
||||
EXPECTED_GRID = ((1, 18, 28),)
|
||||
|
||||
|
||||
def _load_engine(path: Path) -> torch.nn.Module:
|
||||
# Importing Torch-TensorRT registers the serialized engine operators used by
|
||||
# the ExportedProgram.
|
||||
import torch_tensorrt # noqa: F401
|
||||
|
||||
started = time.perf_counter()
|
||||
engine = torch.export.load(path).module().cuda()
|
||||
LOGGER.info(
|
||||
"Loaded Qwen3-VL TensorRT vision engine path=%s elapsed=%.3fs",
|
||||
path,
|
||||
time.perf_counter() - started,
|
||||
)
|
||||
return engine
|
||||
|
||||
|
||||
def _grid_tuple(grid: torch.Tensor) -> tuple[tuple[int, ...], ...]:
|
||||
return tuple(tuple(int(value) for value in row) for row in grid.cpu().tolist())
|
||||
|
||||
|
||||
def install_bridge() -> bool:
|
||||
engine_value = os.environ.get(ENGINE_ENV)
|
||||
if not engine_value:
|
||||
return False
|
||||
engine_path = Path(engine_value).expanduser().resolve()
|
||||
if not engine_path.is_file():
|
||||
raise FileNotFoundError(f"TensorRT vision engine not found: {engine_path}")
|
||||
|
||||
from sglang.srt.models.qwen3_vl import Qwen3VLForConditionalGeneration
|
||||
|
||||
if getattr(Qwen3VLForConditionalGeneration, "_trt_bridge_installed", False):
|
||||
return True
|
||||
|
||||
native_get_image_feature = Qwen3VLForConditionalGeneration.get_image_feature
|
||||
|
||||
def get_image_feature(self: Any, items: list[Any]) -> torch.Tensor:
|
||||
image_grid_thw = torch.concat(
|
||||
[item.image_grid_thw for item in items], dim=0
|
||||
)
|
||||
if _grid_tuple(image_grid_thw) != EXPECTED_GRID:
|
||||
self._trt_bridge_fallbacks = getattr(self, "_trt_bridge_fallbacks", 0) + 1
|
||||
return native_get_image_feature(self, items)
|
||||
|
||||
engine = getattr(self, "_trt_vision_engine", None)
|
||||
if engine is None:
|
||||
engine = _load_engine(engine_path)
|
||||
self._trt_vision_engine = engine
|
||||
|
||||
pixel_values = torch.cat([item.feature for item in items], dim=0).to(
|
||||
device="cuda", dtype=torch.bfloat16
|
||||
)
|
||||
outputs = engine(pixel_values.contiguous())
|
||||
# Output 0 is the unmerged vision state. SGLang consumes the merged
|
||||
# language embedding followed by all three packed deep-stack features.
|
||||
packed = torch.cat(tuple(outputs[1:]), dim=-1)
|
||||
if packed.shape != (126, 8192):
|
||||
raise RuntimeError(
|
||||
f"Unexpected TensorRT packed vision shape: {tuple(packed.shape)}"
|
||||
)
|
||||
self._trt_bridge_hits = getattr(self, "_trt_bridge_hits", 0) + 1
|
||||
return packed
|
||||
|
||||
Qwen3VLForConditionalGeneration.get_image_feature = get_image_feature
|
||||
Qwen3VLForConditionalGeneration._trt_bridge_installed = True
|
||||
LOGGER.info(
|
||||
"Installed static Qwen3-VL TensorRT/SGLang bridge engine=%s grid=%s",
|
||||
engine_path,
|
||||
EXPECTED_GRID,
|
||||
)
|
||||
return True
|
||||
|
||||
|
||||
install_bridge()
|
||||
|
||||
|
||||
def main() -> None:
|
||||
parser = argparse.ArgumentParser(description=__doc__)
|
||||
parser.add_argument("--smoke-test", type=Path)
|
||||
args = parser.parse_args()
|
||||
if args.smoke_test is None:
|
||||
return
|
||||
engine = _load_engine(args.smoke_test.resolve())
|
||||
sample = torch.zeros((504, 1536), device="cuda", dtype=torch.bfloat16)
|
||||
with torch.inference_mode():
|
||||
outputs = engine(sample)
|
||||
torch.cuda.synchronize()
|
||||
print([list(output.shape) for output in outputs])
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,389 @@
|
||||
"""Probe and benchmark a real TensorRT vision path for Qwen3-VL.
|
||||
|
||||
The experiment deliberately compiles only the vision tower. It reports
|
||||
TensorRT graph coverage, numerical drift, isolated vision latency, and (when
|
||||
conversion succeeds) can be extended to the unchanged language decoder.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import json
|
||||
import platform
|
||||
import statistics
|
||||
import time
|
||||
from datetime import UTC, datetime
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
import torch_tensorrt
|
||||
from PIL import Image
|
||||
from qwen3_vl_transformers import (
|
||||
aggregate,
|
||||
prepare_inputs,
|
||||
resize_to_longest_edge,
|
||||
run_sample,
|
||||
)
|
||||
from transformers import AutoModelForImageTextToText, AutoProcessor
|
||||
from transformers.models.qwen3_vl.modeling_qwen3_vl import (
|
||||
BaseModelOutputWithDeepstackFeatures,
|
||||
get_vision_bilinear_indices_and_weights,
|
||||
get_vision_cu_seqlens,
|
||||
get_vision_position_ids,
|
||||
)
|
||||
|
||||
|
||||
class StaticVisionTensorOutputs(torch.nn.Module):
|
||||
"""Tensor-only vision tower with fixed-shape positional metadata.
|
||||
|
||||
Transformers derives this metadata from ``grid_thw`` using Python integer
|
||||
conversions. Hoisting it is both export-safe and valid for our explicitly
|
||||
static benchmark shape.
|
||||
"""
|
||||
|
||||
def __init__(self, visual: torch.nn.Module, grid_thw: torch.Tensor) -> None:
|
||||
super().__init__()
|
||||
self.visual = visual
|
||||
indices, weights = get_vision_bilinear_indices_and_weights(
|
||||
grid_thw,
|
||||
num_grid_per_side=visual.num_grid_per_side,
|
||||
spatial_merge_size=visual.config.spatial_merge_size,
|
||||
kwargs={},
|
||||
)
|
||||
position_ids = get_vision_position_ids(
|
||||
grid_thw, visual.spatial_merge_size, kwargs={}
|
||||
)
|
||||
cu_seqlens = get_vision_cu_seqlens(grid_thw, kwargs={})
|
||||
self.register_buffer("bilinear_indices", indices)
|
||||
self.register_buffer("bilinear_weights", weights)
|
||||
self.register_buffer("position_ids", position_ids)
|
||||
self.register_buffer("cu_seqlens", cu_seqlens)
|
||||
|
||||
def forward(self, pixel_values: torch.Tensor) -> tuple[torch.Tensor, ...]:
|
||||
hidden_states = self.visual.patch_embed(pixel_values)
|
||||
pos_embeds = (
|
||||
self.visual.pos_embed(self.bilinear_indices)
|
||||
* self.bilinear_weights[:, :, None]
|
||||
).sum(0)
|
||||
hidden_states = hidden_states + pos_embeds.to(hidden_states.dtype)
|
||||
rotary_pos_emb = self.visual.rotary_pos_emb(self.position_ids)
|
||||
seq_len, _ = hidden_states.size()
|
||||
hidden_states = hidden_states.reshape(seq_len, -1)
|
||||
rotary_pos_emb = rotary_pos_emb.reshape(seq_len, -1)
|
||||
embedding = torch.cat((rotary_pos_emb, rotary_pos_emb), dim=-1)
|
||||
position_embeddings = (embedding.cos(), embedding.sin())
|
||||
deepstack_features = []
|
||||
for layer_num, block in enumerate(self.visual.blocks):
|
||||
hidden_states = block(
|
||||
hidden_states,
|
||||
cu_seqlens=self.cu_seqlens,
|
||||
position_embeddings=position_embeddings,
|
||||
)
|
||||
if layer_num in self.visual.deepstack_visual_indexes:
|
||||
merger_index = self.visual.deepstack_visual_indexes.index(layer_num)
|
||||
deepstack_features.append(
|
||||
self.visual.deepstack_merger_list[merger_index](hidden_states)
|
||||
)
|
||||
return (
|
||||
hidden_states,
|
||||
self.visual.merger(hidden_states),
|
||||
*deepstack_features,
|
||||
)
|
||||
|
||||
|
||||
class CompiledVisionAdapter(torch.nn.Module):
|
||||
"""Restore the Transformers vision API around a compiled tensor graph."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
compiled: torch.nn.Module,
|
||||
*,
|
||||
dtype: torch.dtype,
|
||||
spatial_merge_size: int,
|
||||
) -> None:
|
||||
super().__init__()
|
||||
self.compiled = compiled
|
||||
self._output_dtype = dtype
|
||||
self.spatial_merge_size = spatial_merge_size
|
||||
|
||||
@property
|
||||
def dtype(self) -> torch.dtype:
|
||||
return self._output_dtype
|
||||
|
||||
def forward(
|
||||
self,
|
||||
pixel_values: torch.Tensor,
|
||||
grid_thw: torch.Tensor | None = None,
|
||||
return_dict: bool = True,
|
||||
**_: Any,
|
||||
) -> BaseModelOutputWithDeepstackFeatures | tuple[torch.Tensor, ...]:
|
||||
del grid_thw
|
||||
outputs = self.compiled(pixel_values)
|
||||
if not return_dict:
|
||||
return outputs
|
||||
return BaseModelOutputWithDeepstackFeatures(
|
||||
last_hidden_state=outputs[0],
|
||||
pooler_output=outputs[1],
|
||||
deepstack_features=list(outputs[2:]),
|
||||
)
|
||||
|
||||
|
||||
def timed_samples(
|
||||
module: torch.nn.Module,
|
||||
pixel_values: torch.Tensor,
|
||||
*,
|
||||
warmups: int,
|
||||
runs: int,
|
||||
) -> tuple[tuple[torch.Tensor, ...], list[float]]:
|
||||
output: tuple[torch.Tensor, ...] | None = None
|
||||
samples: list[float] = []
|
||||
with torch.inference_mode():
|
||||
for index in range(warmups + runs):
|
||||
torch.cuda.synchronize()
|
||||
started = time.perf_counter()
|
||||
output = module(pixel_values)
|
||||
torch.cuda.synchronize()
|
||||
elapsed_ms = (time.perf_counter() - started) * 1000
|
||||
if index >= warmups:
|
||||
samples.append(elapsed_ms)
|
||||
assert output is not None
|
||||
return output, samples
|
||||
|
||||
|
||||
def tensor_errors(
|
||||
eager: tuple[torch.Tensor, ...], compiled: tuple[torch.Tensor, ...]
|
||||
) -> list[dict[str, Any]]:
|
||||
errors = []
|
||||
for index, (reference, candidate) in enumerate(zip(eager, compiled, strict=True)):
|
||||
difference = (reference.float() - candidate.float()).abs()
|
||||
errors.append(
|
||||
{
|
||||
"output_index": index,
|
||||
"shape": list(reference.shape),
|
||||
"max_absolute_error": float(difference.max()),
|
||||
"mean_absolute_error": float(difference.mean()),
|
||||
"cosine_similarity": float(
|
||||
torch.nn.functional.cosine_similarity(
|
||||
reference.float().flatten(),
|
||||
candidate.float().flatten(),
|
||||
dim=0,
|
||||
)
|
||||
),
|
||||
}
|
||||
)
|
||||
return errors
|
||||
|
||||
|
||||
def graph_coverage(module: torch.nn.Module) -> dict[str, Any]:
|
||||
graph = getattr(module, "graph", None)
|
||||
if graph is None:
|
||||
return {"available": False}
|
||||
nodes = list(graph.nodes)
|
||||
call_modules = [node for node in nodes if node.op == "call_module"]
|
||||
targets = [str(node.target) for node in call_modules]
|
||||
engine_targets = [target for target in targets if "run_on_acc" in target]
|
||||
fallback_targets = [target for target in targets if "run_on_gpu" in target]
|
||||
return {
|
||||
"available": True,
|
||||
"graph_nodes": len(nodes),
|
||||
"call_modules": targets,
|
||||
"tensorrt_engine_partitions": len(engine_targets),
|
||||
"pytorch_fallback_partitions": len(fallback_targets),
|
||||
}
|
||||
|
||||
|
||||
def main() -> None:
|
||||
parser = argparse.ArgumentParser(description=__doc__)
|
||||
parser.add_argument("--image", type=Path, required=True)
|
||||
parser.add_argument("--model", default="Qwen/Qwen3-VL-2B-Instruct")
|
||||
parser.add_argument(
|
||||
"--prompt", default="Describe this image precisely in one sentence."
|
||||
)
|
||||
parser.add_argument("--longest-edge", type=int, default=448)
|
||||
parser.add_argument("--warmups", type=int, default=5)
|
||||
parser.add_argument("--runs", type=int, default=20)
|
||||
parser.add_argument("--generation-warmups", type=int, default=1)
|
||||
parser.add_argument("--generation-runs", type=int, default=3)
|
||||
parser.add_argument("--max-new-tokens", type=int, default=96)
|
||||
parser.add_argument("--min-block-size", type=int, default=5)
|
||||
parser.add_argument("--optimization-level", type=int, default=3)
|
||||
parser.add_argument("--require-full-compilation", action="store_true")
|
||||
parser.add_argument(
|
||||
"--save-engine",
|
||||
type=Path,
|
||||
help="Serialize the compiled vision graph as a portable ExportedProgram.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--output",
|
||||
type=Path,
|
||||
default=Path("benchmarks/results/qwen3-vl-2b-tensorrt-vision.json"),
|
||||
)
|
||||
args = parser.parse_args()
|
||||
if not torch.cuda.is_available():
|
||||
raise RuntimeError("CUDA is required")
|
||||
|
||||
image = resize_to_longest_edge(
|
||||
Image.open(args.image).convert("RGB"), args.longest_edge
|
||||
)
|
||||
load_started = time.perf_counter()
|
||||
processor = AutoProcessor.from_pretrained(args.model)
|
||||
model = AutoModelForImageTextToText.from_pretrained(
|
||||
args.model,
|
||||
dtype=torch.bfloat16,
|
||||
attn_implementation="sdpa",
|
||||
device_map="cuda",
|
||||
).eval()
|
||||
torch.cuda.synchronize()
|
||||
load_seconds = time.perf_counter() - load_started
|
||||
|
||||
inputs = prepare_inputs(
|
||||
processor,
|
||||
image,
|
||||
args.prompt,
|
||||
min_pixels=None,
|
||||
max_pixels=None,
|
||||
)
|
||||
pixel_values = inputs["pixel_values"].to("cuda", dtype=torch.bfloat16)
|
||||
grid_thw = inputs["image_grid_thw"].to("cuda")
|
||||
visual = StaticVisionTensorOutputs(model.model.visual, grid_thw).eval()
|
||||
|
||||
eager_output, eager_ms = timed_samples(
|
||||
visual,
|
||||
pixel_values,
|
||||
warmups=args.warmups,
|
||||
runs=args.runs,
|
||||
)
|
||||
eager_generation = []
|
||||
for index in range(args.generation_warmups + args.generation_runs):
|
||||
sample = run_sample(
|
||||
model,
|
||||
processor,
|
||||
image,
|
||||
args.prompt,
|
||||
max_new_tokens=args.max_new_tokens,
|
||||
cache_implementation="static",
|
||||
min_pixels=None,
|
||||
max_pixels=None,
|
||||
disable_compile=False,
|
||||
)
|
||||
if index >= args.generation_warmups:
|
||||
eager_generation.append(sample)
|
||||
compile_started = time.perf_counter()
|
||||
compiled = torch_tensorrt.compile(
|
||||
visual,
|
||||
ir="dynamo",
|
||||
arg_inputs=(pixel_values,),
|
||||
enabled_precisions={torch.bfloat16},
|
||||
min_block_size=args.min_block_size,
|
||||
optimization_level=args.optimization_level,
|
||||
require_full_compilation=args.require_full_compilation,
|
||||
pass_through_build_failures=True,
|
||||
enable_experimental_decompositions=True,
|
||||
cache_built_engines=True,
|
||||
reuse_cached_engines=True,
|
||||
engine_cache_dir="benchmarks/results/tensorrt-engine-cache",
|
||||
)
|
||||
torch.cuda.synchronize()
|
||||
compile_seconds = time.perf_counter() - compile_started
|
||||
compiled_output, compiled_ms = timed_samples(
|
||||
compiled,
|
||||
pixel_values,
|
||||
warmups=args.warmups,
|
||||
runs=args.runs,
|
||||
)
|
||||
if args.save_engine is not None:
|
||||
args.save_engine.parent.mkdir(parents=True, exist_ok=True)
|
||||
torch_tensorrt.save(
|
||||
compiled,
|
||||
str(args.save_engine),
|
||||
output_format="exported_program",
|
||||
pickle_protocol=4,
|
||||
)
|
||||
original_visual = model.model.visual
|
||||
model.model.visual = CompiledVisionAdapter(
|
||||
compiled,
|
||||
dtype=original_visual.dtype,
|
||||
spatial_merge_size=original_visual.spatial_merge_size,
|
||||
)
|
||||
tensorrt_generation = []
|
||||
for index in range(args.generation_warmups + args.generation_runs):
|
||||
sample = run_sample(
|
||||
model,
|
||||
processor,
|
||||
image,
|
||||
args.prompt,
|
||||
max_new_tokens=args.max_new_tokens,
|
||||
cache_implementation="static",
|
||||
min_pixels=None,
|
||||
max_pixels=None,
|
||||
disable_compile=False,
|
||||
)
|
||||
if index >= args.generation_warmups:
|
||||
tensorrt_generation.append(sample)
|
||||
|
||||
eager_median = statistics.median(eager_ms)
|
||||
compiled_median = statistics.median(compiled_ms)
|
||||
artifact = {
|
||||
"schema": "comfyui-vlm/tensorrt-vision-probe",
|
||||
"version": 1,
|
||||
"created_at": datetime.now(UTC).isoformat(),
|
||||
"model": args.model,
|
||||
"media": {
|
||||
"path": str(args.image.resolve()),
|
||||
"processed_size": list(image.size),
|
||||
"pixel_values_shape": list(pixel_values.shape),
|
||||
"image_grid_thw": grid_thw.cpu().tolist(),
|
||||
},
|
||||
"environment": {
|
||||
"platform": platform.platform(),
|
||||
"python": platform.python_version(),
|
||||
"torch": torch.__version__,
|
||||
"cuda": torch.version.cuda,
|
||||
"torch_tensorrt": torch_tensorrt.__version__,
|
||||
"tensorrt": __import__("tensorrt").__version__,
|
||||
"transformers": __import__("transformers").__version__,
|
||||
"gpu": torch.cuda.get_device_name(),
|
||||
},
|
||||
"configuration": {
|
||||
"precision": "bfloat16",
|
||||
"min_block_size": args.min_block_size,
|
||||
"optimization_level": args.optimization_level,
|
||||
"require_full_compilation": args.require_full_compilation,
|
||||
"warmups": args.warmups,
|
||||
"runs": args.runs,
|
||||
"generation_warmups": args.generation_warmups,
|
||||
"generation_runs": args.generation_runs,
|
||||
},
|
||||
"model_load_seconds": round(load_seconds, 3),
|
||||
"compile_seconds": round(compile_seconds, 3),
|
||||
"coverage": graph_coverage(compiled),
|
||||
"fidelity": tensor_errors(eager_output, compiled_output),
|
||||
"latency_ms": {
|
||||
"eager_samples": [round(value, 3) for value in eager_ms],
|
||||
"tensorrt_samples": [round(value, 3) for value in compiled_ms],
|
||||
"eager_median": round(eager_median, 3),
|
||||
"tensorrt_median": round(compiled_median, 3),
|
||||
"speedup": round(eager_median / compiled_median, 3),
|
||||
},
|
||||
"generation": {
|
||||
"eager": aggregate(eager_generation),
|
||||
"tensorrt": aggregate(tensorrt_generation),
|
||||
"exact_output_match": all(
|
||||
sample["output_sha256"] == eager_generation[0]["output_sha256"]
|
||||
for sample in tensorrt_generation
|
||||
),
|
||||
"eager_output": eager_generation[0]["output"],
|
||||
"tensorrt_output": tensorrt_generation[0]["output"],
|
||||
"eager_samples": eager_generation,
|
||||
"tensorrt_samples": tensorrt_generation,
|
||||
},
|
||||
}
|
||||
args.output.parent.mkdir(parents=True, exist_ok=True)
|
||||
args.output.write_text(json.dumps(artifact, indent=2) + "\n", encoding="utf-8")
|
||||
print(json.dumps(artifact, indent=2), flush=True)
|
||||
print(args.output, flush=True)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,351 @@
|
||||
"""Direct Qwen3-VL Transformers benchmark with quality-preserving artifacts.
|
||||
|
||||
This runner measures the same local model path used by Modern VLM without
|
||||
requiring a running ComfyUI server. It records preprocessing, user-visible
|
||||
time-to-first-text, end-to-end latency, decode throughput, peak VRAM, and the
|
||||
complete output for exact cross-iteration comparisons.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import hashlib
|
||||
import json
|
||||
import math
|
||||
import os
|
||||
import platform
|
||||
import statistics
|
||||
import subprocess
|
||||
import threading
|
||||
import time
|
||||
from datetime import UTC, datetime
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
from PIL import Image
|
||||
from transformers import (
|
||||
AutoModelForImageTextToText,
|
||||
AutoProcessor,
|
||||
TextIteratorStreamer,
|
||||
)
|
||||
|
||||
|
||||
def percentile(values: list[float], quantile: float) -> float:
|
||||
ordered = sorted(values)
|
||||
position = (len(ordered) - 1) * quantile
|
||||
lower = math.floor(position)
|
||||
upper = math.ceil(position)
|
||||
if lower == upper:
|
||||
return ordered[lower]
|
||||
return ordered[lower] * (upper - position) + ordered[upper] * (position - lower)
|
||||
|
||||
|
||||
def git_value(*args: str) -> str | None:
|
||||
try:
|
||||
return subprocess.check_output(
|
||||
["git", *args], text=True, stderr=subprocess.DEVNULL
|
||||
).strip()
|
||||
except (OSError, subprocess.CalledProcessError):
|
||||
return None
|
||||
|
||||
|
||||
def sha256_file(path: Path) -> str:
|
||||
digest = hashlib.sha256()
|
||||
with path.open("rb") as handle:
|
||||
for chunk in iter(lambda: handle.read(1024 * 1024), b""):
|
||||
digest.update(chunk)
|
||||
return digest.hexdigest()
|
||||
|
||||
|
||||
def resize_to_longest_edge(image: Image.Image, longest_edge: int | None) -> Image.Image:
|
||||
if longest_edge is None or max(image.size) <= longest_edge:
|
||||
return image
|
||||
scale = longest_edge / max(image.size)
|
||||
size = (
|
||||
max(1, round(image.width * scale)),
|
||||
max(1, round(image.height * scale)),
|
||||
)
|
||||
return image.resize(size, Image.Resampling.BOX)
|
||||
|
||||
|
||||
def prepare_inputs(
|
||||
processor: Any,
|
||||
image: Image.Image,
|
||||
prompt: str,
|
||||
*,
|
||||
min_pixels: int | None,
|
||||
max_pixels: int | None,
|
||||
) -> dict[str, torch.Tensor]:
|
||||
image_part: dict[str, Any] = {"type": "image", "image": image}
|
||||
if min_pixels is not None:
|
||||
image_part["min_pixels"] = min_pixels
|
||||
if max_pixels is not None:
|
||||
image_part["max_pixels"] = max_pixels
|
||||
messages = [
|
||||
{
|
||||
"role": "user",
|
||||
"content": [image_part, {"type": "text", "text": prompt}],
|
||||
}
|
||||
]
|
||||
return processor.apply_chat_template(
|
||||
messages,
|
||||
add_generation_prompt=True,
|
||||
tokenize=True,
|
||||
return_dict=True,
|
||||
return_tensors="pt",
|
||||
)
|
||||
|
||||
|
||||
def run_sample(
|
||||
model: Any,
|
||||
processor: Any,
|
||||
image: Image.Image,
|
||||
prompt: str,
|
||||
*,
|
||||
max_new_tokens: int,
|
||||
cache_implementation: str,
|
||||
min_pixels: int | None,
|
||||
max_pixels: int | None,
|
||||
disable_compile: bool,
|
||||
) -> dict[str, Any]:
|
||||
torch.cuda.reset_peak_memory_stats()
|
||||
torch.cuda.synchronize()
|
||||
started = time.perf_counter()
|
||||
inputs = prepare_inputs(
|
||||
processor,
|
||||
image,
|
||||
prompt,
|
||||
min_pixels=min_pixels,
|
||||
max_pixels=max_pixels,
|
||||
)
|
||||
prepared_at = time.perf_counter()
|
||||
inputs = {name: value.to(model.device) for name, value in inputs.items()}
|
||||
input_length = int(inputs["input_ids"].shape[-1])
|
||||
streamer = TextIteratorStreamer(
|
||||
processor.tokenizer,
|
||||
skip_prompt=True,
|
||||
skip_special_tokens=True,
|
||||
clean_up_tokenization_spaces=False,
|
||||
)
|
||||
generated: list[torch.Tensor] = []
|
||||
errors: list[BaseException] = []
|
||||
|
||||
def generate() -> None:
|
||||
try:
|
||||
with torch.inference_mode():
|
||||
generated.append(
|
||||
model.generate(
|
||||
**inputs,
|
||||
max_new_tokens=max_new_tokens,
|
||||
do_sample=False,
|
||||
cache_implementation=cache_implementation,
|
||||
disable_compile=disable_compile,
|
||||
streamer=streamer,
|
||||
)
|
||||
)
|
||||
except BaseException as exc:
|
||||
errors.append(exc)
|
||||
streamer.end()
|
||||
|
||||
first_text_at: float | None = None
|
||||
chunks: list[str] = []
|
||||
worker = threading.Thread(target=generate, daemon=True)
|
||||
worker.start()
|
||||
for chunk in streamer:
|
||||
if chunk and first_text_at is None:
|
||||
first_text_at = time.perf_counter()
|
||||
chunks.append(chunk)
|
||||
worker.join()
|
||||
if errors:
|
||||
raise errors[0]
|
||||
torch.cuda.synchronize()
|
||||
finished = time.perf_counter()
|
||||
output_ids = generated[0][:, input_length:]
|
||||
output_tokens = int(output_ids.shape[-1])
|
||||
output = processor.batch_decode(
|
||||
output_ids,
|
||||
skip_special_tokens=True,
|
||||
clean_up_tokenization_spaces=False,
|
||||
)[0].strip()
|
||||
ttft_seconds = (first_text_at or finished) - started
|
||||
decode_seconds = max(0.0, finished - (first_text_at or finished))
|
||||
return {
|
||||
"preprocess_ms": round((prepared_at - started) * 1000, 3),
|
||||
"ttft_ms": round(ttft_seconds * 1000, 3),
|
||||
"e2e_ms": round((finished - started) * 1000, 3),
|
||||
"output_tokens": output_tokens,
|
||||
"output_tokens_per_second": (
|
||||
round(max(0, output_tokens - 1) / decode_seconds, 3)
|
||||
if output_tokens > 1 and decode_seconds > 0
|
||||
else None
|
||||
),
|
||||
"peak_vram_gib": round(torch.cuda.max_memory_allocated() / 1024**3, 3),
|
||||
"input_tokens": input_length,
|
||||
"vision_tokens": int(inputs.get("pixel_values", torch.empty(0)).shape[0]),
|
||||
"output": output,
|
||||
"output_sha256": hashlib.sha256(output.encode("utf-8")).hexdigest(),
|
||||
}
|
||||
|
||||
|
||||
def aggregate(samples: list[dict[str, Any]]) -> dict[str, Any]:
|
||||
def metric(name: str) -> list[float]:
|
||||
return [float(sample[name]) for sample in samples]
|
||||
|
||||
rates = [
|
||||
float(sample["output_tokens_per_second"])
|
||||
for sample in samples
|
||||
if sample["output_tokens_per_second"] is not None
|
||||
]
|
||||
return {
|
||||
"preprocess_ms_mean": round(statistics.fmean(metric("preprocess_ms")), 3),
|
||||
"ttft_ms": {
|
||||
"p50": round(percentile(metric("ttft_ms"), 0.50), 3),
|
||||
"p95": round(percentile(metric("ttft_ms"), 0.95), 3),
|
||||
},
|
||||
"e2e_ms": {
|
||||
"p50": round(percentile(metric("e2e_ms"), 0.50), 3),
|
||||
"p95": round(percentile(metric("e2e_ms"), 0.95), 3),
|
||||
},
|
||||
"output_tokens_per_second_mean": round(statistics.fmean(rates), 3),
|
||||
"peak_vram_gib": round(max(metric("peak_vram_gib")), 3),
|
||||
"output_tokens_mean": round(statistics.fmean(metric("output_tokens")), 3),
|
||||
"outputs_identical": len({sample["output_sha256"] for sample in samples}) == 1,
|
||||
}
|
||||
|
||||
|
||||
def main() -> None:
|
||||
parser = argparse.ArgumentParser(description=__doc__)
|
||||
parser.add_argument("--image", type=Path, required=True)
|
||||
parser.add_argument("--prompt", default="Describe this image precisely in one sentence.")
|
||||
parser.add_argument("--model", default="Qwen/Qwen3-VL-2B-Instruct")
|
||||
parser.add_argument("--label", required=True)
|
||||
parser.add_argument(
|
||||
"--attention",
|
||||
choices=("sdpa", "flash_attention_2", "eager"),
|
||||
default="sdpa",
|
||||
)
|
||||
parser.add_argument("--cache", choices=("dynamic", "static"), default="dynamic")
|
||||
parser.add_argument("--disable-compile", action="store_true")
|
||||
parser.add_argument("--min-pixels", type=int)
|
||||
parser.add_argument("--max-pixels", type=int)
|
||||
parser.add_argument("--longest-edge", type=int)
|
||||
parser.add_argument("--max-new-tokens", type=int, default=96)
|
||||
parser.add_argument("--warmups", type=int, default=2)
|
||||
parser.add_argument("--runs", type=int, default=5)
|
||||
parser.add_argument("--expected-output-sha256")
|
||||
parser.add_argument(
|
||||
"--float32-matmul-precision",
|
||||
choices=("highest", "high", "medium"),
|
||||
default="highest",
|
||||
)
|
||||
parser.add_argument("--output-dir", type=Path, default=Path("benchmarks/results"))
|
||||
args = parser.parse_args()
|
||||
if not torch.cuda.is_available():
|
||||
raise RuntimeError("This benchmark requires a CUDA GPU.")
|
||||
if args.runs < 1 or args.warmups < 0:
|
||||
parser.error("--runs must be positive and --warmups non-negative")
|
||||
torch.set_float32_matmul_precision(args.float32_matmul_precision)
|
||||
image_path = args.image.resolve()
|
||||
source_image = Image.open(image_path).convert("RGB")
|
||||
image = resize_to_longest_edge(source_image, args.longest_edge)
|
||||
|
||||
load_started = time.perf_counter()
|
||||
processor = AutoProcessor.from_pretrained(args.model)
|
||||
model = AutoModelForImageTextToText.from_pretrained(
|
||||
args.model,
|
||||
dtype=torch.bfloat16,
|
||||
attn_implementation=args.attention,
|
||||
device_map="cuda",
|
||||
).eval()
|
||||
torch.cuda.synchronize()
|
||||
load_seconds = time.perf_counter() - load_started
|
||||
|
||||
samples = []
|
||||
for index in range(args.warmups + args.runs):
|
||||
sample = run_sample(
|
||||
model,
|
||||
processor,
|
||||
image,
|
||||
args.prompt,
|
||||
max_new_tokens=args.max_new_tokens,
|
||||
cache_implementation=args.cache,
|
||||
min_pixels=args.min_pixels,
|
||||
max_pixels=args.max_pixels,
|
||||
disable_compile=args.disable_compile,
|
||||
)
|
||||
print(
|
||||
f"{index + 1}/{args.warmups + args.runs} "
|
||||
f"ttft={sample['ttft_ms']:.1f}ms "
|
||||
f"e2e={sample['e2e_ms']:.1f}ms "
|
||||
f"tok/s={sample['output_tokens_per_second']}"
|
||||
)
|
||||
if index >= args.warmups:
|
||||
samples.append(sample)
|
||||
|
||||
artifact = {
|
||||
"schema": "comfyui-vlm/transformers-benchmark",
|
||||
"version": 1,
|
||||
"created_at": datetime.now(UTC).isoformat(),
|
||||
"label": args.label,
|
||||
"model": args.model,
|
||||
"git_commit": git_value("rev-parse", "HEAD"),
|
||||
"git_dirty": bool(git_value("status", "--porcelain")),
|
||||
"media": {
|
||||
"path": os.fspath(image_path),
|
||||
"sha256": sha256_file(image_path),
|
||||
"source_width": source_image.width,
|
||||
"source_height": source_image.height,
|
||||
"processed_width": image.width,
|
||||
"processed_height": image.height,
|
||||
},
|
||||
"environment": {
|
||||
"platform": platform.platform(),
|
||||
"python": platform.python_version(),
|
||||
"torch": torch.__version__,
|
||||
"cuda": torch.version.cuda,
|
||||
"gpu": torch.cuda.get_device_name(),
|
||||
"transformers": __import__("transformers").__version__,
|
||||
"flash_attn": (
|
||||
__import__("flash_attn").__version__
|
||||
if args.attention == "flash_attention_2"
|
||||
else None
|
||||
),
|
||||
},
|
||||
"settings": {
|
||||
"attention": args.attention,
|
||||
"cache": args.cache,
|
||||
"disable_compile": args.disable_compile,
|
||||
"min_pixels": args.min_pixels,
|
||||
"max_pixels": args.max_pixels,
|
||||
"longest_edge": args.longest_edge,
|
||||
"max_new_tokens": args.max_new_tokens,
|
||||
"warmups": args.warmups,
|
||||
"runs": args.runs,
|
||||
"float32_matmul_precision": args.float32_matmul_precision,
|
||||
},
|
||||
"model_load_seconds": round(load_seconds, 3),
|
||||
"quality_gate": {
|
||||
"method": "byte-identical output SHA-256",
|
||||
"reference_sha256": args.expected_output_sha256,
|
||||
"passed": (
|
||||
all(
|
||||
sample["output_sha256"] == args.expected_output_sha256
|
||||
for sample in samples
|
||||
)
|
||||
if args.expected_output_sha256
|
||||
else None
|
||||
),
|
||||
},
|
||||
"summary": aggregate(samples),
|
||||
"samples": samples,
|
||||
}
|
||||
args.output_dir.mkdir(parents=True, exist_ok=True)
|
||||
output_path = args.output_dir / f"{args.label}.json"
|
||||
output_path.write_text(json.dumps(artifact, indent=2) + "\n", encoding="utf-8")
|
||||
print(json.dumps(artifact["summary"], indent=2))
|
||||
print(output_path)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,4 @@
|
||||
*.log
|
||||
qwen3-vl-2b-sdpa-*.json
|
||||
!qwen3-vl-2b-sdpa-static-edge448-tf32.json
|
||||
qwen3-vl-2b-matrix-tf5.json
|
||||
@@ -0,0 +1,304 @@
|
||||
{
|
||||
"schema": "comfyui-vlm/benchmark-run",
|
||||
"version": 1,
|
||||
"created_at": "2026-08-07T23:33:29.188812+00:00",
|
||||
"label": "qwen3-vl-2b-sglang-flashinfer-448",
|
||||
"backend": "sglang",
|
||||
"suite": "qwen3-vl-2b-demo-448-v1",
|
||||
"model": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"git_commit": "d9584e1e35c4373ef99ac07d7c4a866852363c99",
|
||||
"git_dirty": true,
|
||||
"environment": {
|
||||
"platform": "Linux-6.18.33.2-microsoft-standard-WSL2-x86_64-with-glibc2.35",
|
||||
"python": "3.11.14",
|
||||
"server_base_url": "http://127.0.0.1:30000/v1"
|
||||
},
|
||||
"settings": {
|
||||
"warmups": 3,
|
||||
"runs": 10,
|
||||
"max_tokens": 96,
|
||||
"temperature": 0.0,
|
||||
"quality_tolerance": 1.0
|
||||
},
|
||||
"summary": {
|
||||
"requests": 10,
|
||||
"latency_ms": {
|
||||
"p50": 43.271,
|
||||
"p95": 47.958,
|
||||
"p99": 50.233
|
||||
},
|
||||
"ttft_ms": {
|
||||
"p50": 38.276,
|
||||
"p95": 42.913,
|
||||
"p99": 45.215
|
||||
},
|
||||
"output_tokens_per_second_mean": 393.882,
|
||||
"quality_mean": 0.0
|
||||
},
|
||||
"quality_gate": {
|
||||
"threshold": 1.0,
|
||||
"passed": false
|
||||
},
|
||||
"samples": [
|
||||
{
|
||||
"output": "```",
|
||||
"latency_ms": 43.967,
|
||||
"ttft_ms": 38.911,
|
||||
"completion_tokens": 2,
|
||||
"output_tokens_per_second": 395.577,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 146,
|
||||
"completion_tokens": 2,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 0,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 0.0
|
||||
},
|
||||
{
|
||||
"output": "```",
|
||||
"latency_ms": 44.482,
|
||||
"ttft_ms": 39.396,
|
||||
"completion_tokens": 2,
|
||||
"output_tokens_per_second": 393.213,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 146,
|
||||
"completion_tokens": 2,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 1,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 0.0
|
||||
},
|
||||
{
|
||||
"output": "```",
|
||||
"latency_ms": 44.431,
|
||||
"ttft_ms": 39.33,
|
||||
"completion_tokens": 2,
|
||||
"output_tokens_per_second": 392.065,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 146,
|
||||
"completion_tokens": 2,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 2,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 0.0
|
||||
},
|
||||
{
|
||||
"output": "```",
|
||||
"latency_ms": 50.802,
|
||||
"ttft_ms": 45.791,
|
||||
"completion_tokens": 2,
|
||||
"output_tokens_per_second": 399.098,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 146,
|
||||
"completion_tokens": 2,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 3,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 0.0
|
||||
},
|
||||
{
|
||||
"output": "```",
|
||||
"latency_ms": 41.64,
|
||||
"ttft_ms": 36.399,
|
||||
"completion_tokens": 2,
|
||||
"output_tokens_per_second": 381.592,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 146,
|
||||
"completion_tokens": 2,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 4,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 0.0
|
||||
},
|
||||
{
|
||||
"output": "```",
|
||||
"latency_ms": 42.047,
|
||||
"ttft_ms": 37.063,
|
||||
"completion_tokens": 2,
|
||||
"output_tokens_per_second": 401.332,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 146,
|
||||
"completion_tokens": 2,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 5,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 0.0
|
||||
},
|
||||
{
|
||||
"output": "```",
|
||||
"latency_ms": 42.536,
|
||||
"ttft_ms": 37.641,
|
||||
"completion_tokens": 2,
|
||||
"output_tokens_per_second": 408.589,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 146,
|
||||
"completion_tokens": 2,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 6,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 0.0
|
||||
},
|
||||
{
|
||||
"output": "```",
|
||||
"latency_ms": 43.94,
|
||||
"ttft_ms": 38.958,
|
||||
"completion_tokens": 2,
|
||||
"output_tokens_per_second": 401.461,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 146,
|
||||
"completion_tokens": 2,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 7,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 0.0
|
||||
},
|
||||
{
|
||||
"output": "```",
|
||||
"latency_ms": 42.602,
|
||||
"ttft_ms": 37.429,
|
||||
"completion_tokens": 2,
|
||||
"output_tokens_per_second": 386.593,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 146,
|
||||
"completion_tokens": 2,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 8,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 0.0
|
||||
},
|
||||
{
|
||||
"output": "```",
|
||||
"latency_ms": 42.116,
|
||||
"ttft_ms": 36.844,
|
||||
"completion_tokens": 2,
|
||||
"output_tokens_per_second": 379.305,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 146,
|
||||
"completion_tokens": 2,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 9,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 0.0
|
||||
}
|
||||
]
|
||||
}
|
||||
+304
@@ -0,0 +1,304 @@
|
||||
{
|
||||
"schema": "comfyui-vlm/benchmark-run",
|
||||
"version": 1,
|
||||
"created_at": "2026-08-07T23:51:14.661282+00:00",
|
||||
"label": "qwen3-vl-2b-sglang-0510-transformers-flashinfer-edge448",
|
||||
"backend": "sglang",
|
||||
"suite": "qwen3-vl-2b-demo-448-v1",
|
||||
"model": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"git_commit": "d9584e1e35c4373ef99ac07d7c4a866852363c99",
|
||||
"git_dirty": true,
|
||||
"environment": {
|
||||
"platform": "Linux-6.18.33.2-microsoft-standard-WSL2-x86_64-with-glibc2.35",
|
||||
"python": "3.11.14",
|
||||
"server_base_url": "http://127.0.0.1:30000/v1"
|
||||
},
|
||||
"settings": {
|
||||
"warmups": 3,
|
||||
"runs": 10,
|
||||
"max_tokens": 96,
|
||||
"temperature": 0.0,
|
||||
"quality_tolerance": 1.0
|
||||
},
|
||||
"summary": {
|
||||
"requests": 10,
|
||||
"latency_ms": {
|
||||
"p50": 254.247,
|
||||
"p95": 257.515,
|
||||
"p99": 258.626
|
||||
},
|
||||
"ttft_ms": {
|
||||
"p50": 75.627,
|
||||
"p95": 79.154,
|
||||
"p99": 80.361
|
||||
},
|
||||
"output_tokens_per_second_mean": 173.546,
|
||||
"quality_mean": 1.0
|
||||
},
|
||||
"quality_gate": {
|
||||
"threshold": 1.0,
|
||||
"passed": true
|
||||
},
|
||||
"samples": [
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 254.057,
|
||||
"ttft_ms": 74.753,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 172.891,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 0,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 258.904,
|
||||
"ttft_ms": 80.663,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 173.922,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 1,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 254.891,
|
||||
"ttft_ms": 76.593,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 173.866,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 2,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 252.898,
|
||||
"ttft_ms": 74.213,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 173.489,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 3,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 253.15,
|
||||
"ttft_ms": 74.329,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 173.358,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 4,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 254.437,
|
||||
"ttft_ms": 75.904,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 173.638,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 5,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 253.923,
|
||||
"ttft_ms": 75.351,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 173.599,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 6,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 255.317,
|
||||
"ttft_ms": 76.96,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 173.808,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 7,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 253.695,
|
||||
"ttft_ms": 74.735,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 173.222,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 8,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 255.817,
|
||||
"ttft_ms": 77.31,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 173.662,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 9,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
}
|
||||
]
|
||||
}
|
||||
+304
@@ -0,0 +1,304 @@
|
||||
{
|
||||
"schema": "comfyui-vlm/benchmark-run",
|
||||
"version": 1,
|
||||
"created_at": "2026-08-07T23:54:42.051771+00:00",
|
||||
"label": "qwen3-vl-2b-sglang-0510-native-flashinfer-edge448-concepts",
|
||||
"backend": "sglang",
|
||||
"suite": "qwen3-vl-2b-demo-448-v1",
|
||||
"model": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"git_commit": "d9584e1e35c4373ef99ac07d7c4a866852363c99",
|
||||
"git_dirty": true,
|
||||
"environment": {
|
||||
"platform": "Linux-6.18.33.2-microsoft-standard-WSL2-x86_64-with-glibc2.35",
|
||||
"python": "3.11.14",
|
||||
"server_base_url": "http://127.0.0.1:30000/v1"
|
||||
},
|
||||
"settings": {
|
||||
"warmups": 3,
|
||||
"runs": 10,
|
||||
"max_tokens": 96,
|
||||
"temperature": 0.0,
|
||||
"quality_tolerance": 1.0
|
||||
},
|
||||
"summary": {
|
||||
"requests": 10,
|
||||
"latency_ms": {
|
||||
"p50": 240.643,
|
||||
"p95": 243.55,
|
||||
"p99": 243.925
|
||||
},
|
||||
"ttft_ms": {
|
||||
"p50": 35.228,
|
||||
"p95": 38.264,
|
||||
"p99": 38.455
|
||||
},
|
||||
"output_tokens_per_second_mean": 194.675,
|
||||
"quality_mean": 1.0
|
||||
},
|
||||
"quality_gate": {
|
||||
"threshold": 1.0,
|
||||
"passed": true
|
||||
},
|
||||
"samples": [
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 240.312,
|
||||
"ttft_ms": 34.498,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 194.35,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 0,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 240.597,
|
||||
"ttft_ms": 35.33,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 194.868,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 1,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 240.689,
|
||||
"ttft_ms": 35.043,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 194.509,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 2,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 241.979,
|
||||
"ttft_ms": 36.655,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 194.815,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 3,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 241.043,
|
||||
"ttft_ms": 35.436,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 194.546,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 4,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 240.182,
|
||||
"ttft_ms": 34.754,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 194.716,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 5,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 240.477,
|
||||
"ttft_ms": 35.127,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 194.789,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 6,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 240.458,
|
||||
"ttft_ms": 34.706,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 194.409,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 7,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 244.019,
|
||||
"ttft_ms": 38.503,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 194.631,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 8,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 242.976,
|
||||
"ttft_ms": 37.973,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 195.119,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 9,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
}
|
||||
]
|
||||
}
|
||||
+304
@@ -0,0 +1,304 @@
|
||||
{
|
||||
"schema": "comfyui-vlm/benchmark-run",
|
||||
"version": 1,
|
||||
"created_at": "2026-08-07T23:56:26.751727+00:00",
|
||||
"label": "qwen3-vl-2b-sglang-0510-native-triton-mm-edge448",
|
||||
"backend": "sglang",
|
||||
"suite": "qwen3-vl-2b-demo-448-v1",
|
||||
"model": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"git_commit": "d9584e1e35c4373ef99ac07d7c4a866852363c99",
|
||||
"git_dirty": true,
|
||||
"environment": {
|
||||
"platform": "Linux-6.18.33.2-microsoft-standard-WSL2-x86_64-with-glibc2.35",
|
||||
"python": "3.11.14",
|
||||
"server_base_url": "http://127.0.0.1:30000/v1"
|
||||
},
|
||||
"settings": {
|
||||
"warmups": 3,
|
||||
"runs": 10,
|
||||
"max_tokens": 96,
|
||||
"temperature": 0.0,
|
||||
"quality_tolerance": 1.0
|
||||
},
|
||||
"summary": {
|
||||
"requests": 10,
|
||||
"latency_ms": {
|
||||
"p50": 193.603,
|
||||
"p95": 195.324,
|
||||
"p99": 195.594
|
||||
},
|
||||
"ttft_ms": {
|
||||
"p50": 35.484,
|
||||
"p95": 37.948,
|
||||
"p99": 38.154
|
||||
},
|
||||
"output_tokens_per_second_mean": 196.424,
|
||||
"quality_mean": 1.0
|
||||
},
|
||||
"quality_gate": {
|
||||
"threshold": 1.0,
|
||||
"passed": true
|
||||
},
|
||||
"samples": [
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 194.306,
|
||||
"ttft_ms": 37.462,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 197.649,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 0,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 193.679,
|
||||
"ttft_ms": 36.034,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 196.645,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 1,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 193.82,
|
||||
"ttft_ms": 35.359,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 195.632,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 2,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 195.662,
|
||||
"ttft_ms": 38.205,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 196.879,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 3,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 193.234,
|
||||
"ttft_ms": 35.429,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 196.444,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 4,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 193.526,
|
||||
"ttft_ms": 35.539,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 196.219,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 5,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 192.795,
|
||||
"ttft_ms": 34.703,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 196.088,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 6,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 192.793,
|
||||
"ttft_ms": 34.319,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 195.616,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 7,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 194.911,
|
||||
"ttft_ms": 37.633,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 197.103,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 8,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 193.316,
|
||||
"ttft_ms": 35.129,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 195.97,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 9,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
}
|
||||
]
|
||||
}
|
||||
+304
@@ -0,0 +1,304 @@
|
||||
{
|
||||
"schema": "comfyui-vlm/benchmark-run",
|
||||
"version": 1,
|
||||
"created_at": "2026-08-07T23:59:00.162586+00:00",
|
||||
"label": "qwen3-vl-2b-sglang-0510-native-triton-mm-compile-edge448",
|
||||
"backend": "sglang",
|
||||
"suite": "qwen3-vl-2b-demo-448-v1",
|
||||
"model": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"git_commit": "d9584e1e35c4373ef99ac07d7c4a866852363c99",
|
||||
"git_dirty": true,
|
||||
"environment": {
|
||||
"platform": "Linux-6.18.33.2-microsoft-standard-WSL2-x86_64-with-glibc2.35",
|
||||
"python": "3.11.14",
|
||||
"server_base_url": "http://127.0.0.1:30000/v1"
|
||||
},
|
||||
"settings": {
|
||||
"warmups": 3,
|
||||
"runs": 10,
|
||||
"max_tokens": 96,
|
||||
"temperature": 0.0,
|
||||
"quality_tolerance": 1.0
|
||||
},
|
||||
"summary": {
|
||||
"requests": 10,
|
||||
"latency_ms": {
|
||||
"p50": 190.452,
|
||||
"p95": 194.69,
|
||||
"p99": 195.155
|
||||
},
|
||||
"ttft_ms": {
|
||||
"p50": 37.46,
|
||||
"p95": 40.955,
|
||||
"p99": 41.035
|
||||
},
|
||||
"output_tokens_per_second_mean": 202.626,
|
||||
"quality_mean": 1.0
|
||||
},
|
||||
"quality_gate": {
|
||||
"threshold": 1.0,
|
||||
"passed": true
|
||||
},
|
||||
"samples": [
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 189.65,
|
||||
"ttft_ms": 37.316,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 203.5,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 0,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 191.164,
|
||||
"ttft_ms": 37.604,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 201.876,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 1,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 193.981,
|
||||
"ttft_ms": 41.055,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 202.712,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 2,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 195.271,
|
||||
"ttft_ms": 40.832,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 200.727,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 3,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 188.249,
|
||||
"ttft_ms": 35.967,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 203.569,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 4,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 191.006,
|
||||
"ttft_ms": 36.928,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 201.197,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 5,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 189.897,
|
||||
"ttft_ms": 38.167,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 204.311,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 6,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 191.132,
|
||||
"ttft_ms": 37.715,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 202.064,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 7,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 188.008,
|
||||
"ttft_ms": 35.408,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 203.146,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 8,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"latency_ms": 188.646,
|
||||
"ttft_ms": 36.057,
|
||||
"completion_tokens": 31,
|
||||
"output_tokens_per_second": 203.161,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 175,
|
||||
"completion_tokens": 31,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 9,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,304 @@
|
||||
{
|
||||
"schema": "comfyui-vlm/benchmark-run",
|
||||
"version": 1,
|
||||
"created_at": "2026-08-08T07:29:10.320582+00:00",
|
||||
"label": "qwen3-vl-2b-sglang-tensorrt-bridge-edge448",
|
||||
"backend": "sglang",
|
||||
"suite": "qwen3-vl-2b-demo-448-v1",
|
||||
"model": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"git_commit": "7bfc87bc04789febd24142ed27facde5e5fd54bf",
|
||||
"git_dirty": true,
|
||||
"environment": {
|
||||
"platform": "Linux-6.18.33.2-microsoft-standard-WSL2-x86_64-with-glibc2.35",
|
||||
"python": "3.11.14",
|
||||
"server_base_url": "http://127.0.0.1:30000/v1"
|
||||
},
|
||||
"settings": {
|
||||
"warmups": 3,
|
||||
"runs": 10,
|
||||
"max_tokens": 96,
|
||||
"temperature": 0.0,
|
||||
"quality_tolerance": 1.0
|
||||
},
|
||||
"summary": {
|
||||
"requests": 10,
|
||||
"latency_ms": {
|
||||
"p50": 250.673,
|
||||
"p95": 366.093,
|
||||
"p99": 439.235
|
||||
},
|
||||
"ttft_ms": {
|
||||
"p50": 34.85,
|
||||
"p95": 37.752,
|
||||
"p99": 38.232
|
||||
},
|
||||
"output_tokens_per_second_mean": 176.12,
|
||||
"quality_mean": 1.0
|
||||
},
|
||||
"quality_gate": {
|
||||
"threshold": 1.0,
|
||||
"passed": true
|
||||
},
|
||||
"samples": [
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 254.239,
|
||||
"ttft_ms": 38.352,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 185.282,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 0,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 254.348,
|
||||
"ttft_ms": 35.315,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 182.621,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 1,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 253.791,
|
||||
"ttft_ms": 37.018,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 184.525,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 2,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 249.899,
|
||||
"ttft_ms": 34.987,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 186.122,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 3,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 249.934,
|
||||
"ttft_ms": 34.695,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 185.84,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 4,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 249.348,
|
||||
"ttft_ms": 34.744,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 186.39,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 5,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 250.471,
|
||||
"ttft_ms": 34.284,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 185.025,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 6,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 250.24,
|
||||
"ttft_ms": 34.789,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 185.657,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 7,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 457.52,
|
||||
"ttft_ms": 34.346,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 94.524,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 8,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
},
|
||||
{
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, playfully high-fiving each other as the golden hour light bathes the scene in warm, soft light.",
|
||||
"latency_ms": 250.874,
|
||||
"ttft_ms": 34.911,
|
||||
"completion_tokens": 40,
|
||||
"output_tokens_per_second": 185.218,
|
||||
"usage": {
|
||||
"prompt_tokens": 144,
|
||||
"total_tokens": 184,
|
||||
"completion_tokens": 40,
|
||||
"prompt_tokens_details": null,
|
||||
"reasoning_tokens": 0
|
||||
},
|
||||
"sample": 9,
|
||||
"case_id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"media_sha256": "188eb59f12f8da458d6cb77ce19fb471519a94cd43f6701364593cc5843dce23",
|
||||
"media": {
|
||||
"source_sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"quality": 1.0
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,10 @@
|
||||
# Result artifacts
|
||||
|
||||
Committed JSON files are immutable raw benchmark evidence. Each artifact
|
||||
contains environment identity, input dimensions and token counts, warmups,
|
||||
every measured sample, full model output, quality-gate details, percentiles,
|
||||
VRAM, and speedups.
|
||||
|
||||
Console logs and scratch experiments are ignored. Promote a result by rerunning
|
||||
the benchmark with its final runner and committing the resulting JSON rather
|
||||
than editing an artifact by hand.
|
||||
@@ -0,0 +1,120 @@
|
||||
{
|
||||
"schema": "comfyui-vlm/transformers-benchmark",
|
||||
"version": 1,
|
||||
"created_at": "2026-08-07T23:01:55.323925+00:00",
|
||||
"label": "qwen3-vl-2b-fa2-dynamic-edge448",
|
||||
"model": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"git_commit": "858a4a4998e68bd99b26a12831e861be49904564",
|
||||
"git_dirty": true,
|
||||
"media": {
|
||||
"path": "/home/gokaygokay/ComfyUI_VLM_nodes/benchmarks/media/qwen-demo.jpeg",
|
||||
"sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"environment": {
|
||||
"platform": "Linux-6.18.33.2-microsoft-standard-WSL2-x86_64-with-glibc2.35",
|
||||
"python": "3.11.14",
|
||||
"torch": "2.8.0+cu128",
|
||||
"cuda": "12.8",
|
||||
"gpu": "NVIDIA GeForce RTX 3090",
|
||||
"transformers": "5.12.1",
|
||||
"flash_attn": "2.8.3"
|
||||
},
|
||||
"settings": {
|
||||
"attention": "flash_attention_2",
|
||||
"cache": "dynamic",
|
||||
"disable_compile": false,
|
||||
"min_pixels": null,
|
||||
"max_pixels": null,
|
||||
"longest_edge": 448,
|
||||
"max_new_tokens": 96,
|
||||
"warmups": 2,
|
||||
"runs": 5
|
||||
},
|
||||
"model_load_seconds": 6.845,
|
||||
"quality_gate": {
|
||||
"method": "byte-identical output SHA-256",
|
||||
"reference_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1",
|
||||
"passed": true
|
||||
},
|
||||
"summary": {
|
||||
"preprocess_ms_mean": 4.445,
|
||||
"ttft_ms": {
|
||||
"p50": 106.553,
|
||||
"p95": 114.012
|
||||
},
|
||||
"e2e_ms": {
|
||||
"p50": 1033.269,
|
||||
"p95": 1054.373
|
||||
},
|
||||
"output_tokens_per_second_mean": 32.297,
|
||||
"peak_vram_gib": 4.002,
|
||||
"output_tokens_mean": 31.0,
|
||||
"outputs_identical": true
|
||||
},
|
||||
"samples": [
|
||||
{
|
||||
"preprocess_ms": 4.993,
|
||||
"ttft_ms": 106.308,
|
||||
"e2e_ms": 1029.213,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 32.506,
|
||||
"peak_vram_gib": 4.002,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.881,
|
||||
"ttft_ms": 114.994,
|
||||
"e2e_ms": 1059.265,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 31.771,
|
||||
"peak_vram_gib": 4.002,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.982,
|
||||
"ttft_ms": 110.083,
|
||||
"e2e_ms": 1034.803,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 32.442,
|
||||
"peak_vram_gib": 4.002,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.823,
|
||||
"ttft_ms": 106.553,
|
||||
"e2e_ms": 1033.269,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 32.372,
|
||||
"peak_vram_gib": 4.002,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.547,
|
||||
"ttft_ms": 103.872,
|
||||
"e2e_ms": 1030.035,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 32.392,
|
||||
"peak_vram_gib": 4.002,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,180 @@
|
||||
{
|
||||
"schema": "comfyui-vlm/transformers-benchmark",
|
||||
"version": 1,
|
||||
"created_at": "2026-08-07T23:01:20.543267+00:00",
|
||||
"label": "qwen3-vl-2b-fa2-static-edge448",
|
||||
"model": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"git_commit": "858a4a4998e68bd99b26a12831e861be49904564",
|
||||
"git_dirty": true,
|
||||
"media": {
|
||||
"path": "/home/gokaygokay/ComfyUI_VLM_nodes/benchmarks/media/qwen-demo.jpeg",
|
||||
"sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"environment": {
|
||||
"platform": "Linux-6.18.33.2-microsoft-standard-WSL2-x86_64-with-glibc2.35",
|
||||
"python": "3.11.14",
|
||||
"torch": "2.8.0+cu128",
|
||||
"cuda": "12.8",
|
||||
"gpu": "NVIDIA GeForce RTX 3090",
|
||||
"transformers": "5.12.1",
|
||||
"flash_attn": "2.8.3"
|
||||
},
|
||||
"settings": {
|
||||
"attention": "flash_attention_2",
|
||||
"cache": "static",
|
||||
"disable_compile": false,
|
||||
"min_pixels": null,
|
||||
"max_pixels": null,
|
||||
"longest_edge": 448,
|
||||
"max_new_tokens": 96,
|
||||
"warmups": 6,
|
||||
"runs": 10
|
||||
},
|
||||
"model_load_seconds": 84.208,
|
||||
"quality_gate": {
|
||||
"method": "byte-identical output SHA-256",
|
||||
"reference_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1",
|
||||
"passed": false
|
||||
},
|
||||
"summary": {
|
||||
"preprocess_ms_mean": 4.404,
|
||||
"ttft_ms": {
|
||||
"p50": 265.004,
|
||||
"p95": 273.819
|
||||
},
|
||||
"e2e_ms": {
|
||||
"p50": 3027.985,
|
||||
"p95": 3042.934
|
||||
},
|
||||
"output_tokens_per_second_mean": 34.427,
|
||||
"peak_vram_gib": 4.023,
|
||||
"output_tokens_mean": 96.0,
|
||||
"outputs_identical": true
|
||||
},
|
||||
"samples": [
|
||||
{
|
||||
"preprocess_ms": 5.119,
|
||||
"ttft_ms": 262.459,
|
||||
"e2e_ms": 3016.629,
|
||||
"output_tokens": 96,
|
||||
"output_tokens_per_second": 34.493,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "s:V:col, 1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1",
|
||||
"output_sha256": "ab0d23104f87597bcea8948a30df54a967214df93df48121fb73729585a29026"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.519,
|
||||
"ttft_ms": 265.289,
|
||||
"e2e_ms": 3014.475,
|
||||
"output_tokens": 96,
|
||||
"output_tokens_per_second": 34.556,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "s:V:col, 1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1",
|
||||
"output_sha256": "ab0d23104f87597bcea8948a30df54a967214df93df48121fb73729585a29026"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.943,
|
||||
"ttft_ms": 273.965,
|
||||
"e2e_ms": 3044.849,
|
||||
"output_tokens": 96,
|
||||
"output_tokens_per_second": 34.285,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "s:V:col, 1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1",
|
||||
"output_sha256": "ab0d23104f87597bcea8948a30df54a967214df93df48121fb73729585a29026"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.913,
|
||||
"ttft_ms": 262.719,
|
||||
"e2e_ms": 3039.894,
|
||||
"output_tokens": 96,
|
||||
"output_tokens_per_second": 34.207,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "s:V:col, 1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1",
|
||||
"output_sha256": "ab0d23104f87597bcea8948a30df54a967214df93df48121fb73729585a29026"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.66,
|
||||
"ttft_ms": 261.946,
|
||||
"e2e_ms": 3040.593,
|
||||
"output_tokens": 96,
|
||||
"output_tokens_per_second": 34.189,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "s:V:col, 1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1",
|
||||
"output_sha256": "ab0d23104f87597bcea8948a30df54a967214df93df48121fb73729585a29026"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.929,
|
||||
"ttft_ms": 273.64,
|
||||
"e2e_ms": 2997.449,
|
||||
"output_tokens": 96,
|
||||
"output_tokens_per_second": 34.878,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "s:V:col, 1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1",
|
||||
"output_sha256": "ab0d23104f87597bcea8948a30df54a967214df93df48121fb73729585a29026"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.926,
|
||||
"ttft_ms": 264.987,
|
||||
"e2e_ms": 3028.232,
|
||||
"output_tokens": 96,
|
||||
"output_tokens_per_second": 34.38,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "s:V:col, 1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1",
|
||||
"output_sha256": "ab0d23104f87597bcea8948a30df54a967214df93df48121fb73729585a29026"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.683,
|
||||
"ttft_ms": 267.937,
|
||||
"e2e_ms": 3027.738,
|
||||
"output_tokens": 96,
|
||||
"output_tokens_per_second": 34.423,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "s:V:col, 1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1",
|
||||
"output_sha256": "ab0d23104f87597bcea8948a30df54a967214df93df48121fb73729585a29026"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.571,
|
||||
"ttft_ms": 262.483,
|
||||
"e2e_ms": 3016.256,
|
||||
"output_tokens": 96,
|
||||
"output_tokens_per_second": 34.498,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "s:V:col, 1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1",
|
||||
"output_sha256": "ab0d23104f87597bcea8948a30df54a967214df93df48121fb73729585a29026"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.78,
|
||||
"ttft_ms": 265.021,
|
||||
"e2e_ms": 3029.975,
|
||||
"output_tokens": 96,
|
||||
"output_tokens_per_second": 34.359,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "s:V:col, 1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1:1",
|
||||
"output_sha256": "ab0d23104f87597bcea8948a30df54a967214df93df48121fb73729585a29026"
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,100 @@
|
||||
{
|
||||
"schema_version": 1,
|
||||
"checkpoint": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"safetensors_bytes": 4255140312,
|
||||
"environment": {
|
||||
"gpu": "NVIDIA GeForce RTX 3090 24GB",
|
||||
"filesystem": "WSL2 ext4",
|
||||
"flashpack_revision": "a923a6c",
|
||||
"cache_eviction": "POSIX_FADV_DONTNEED on the measured file only"
|
||||
},
|
||||
"flashpack_reader": {
|
||||
"direct_io": true,
|
||||
"threads": 4,
|
||||
"buffers_per_thread": 2,
|
||||
"chunk_bytes": 33554432,
|
||||
"pinned_staging_bytes": 268435456,
|
||||
"cache_pinned": false
|
||||
},
|
||||
"preparation": {
|
||||
"conversion_seconds": 0.0,
|
||||
"flashpack_bytes": 4255133230,
|
||||
"tensor_count": 625,
|
||||
"sample_exact": {
|
||||
"model.language_model.embed_tokens.weight": true,
|
||||
"model.visual.blocks.17.mlp.linear_fc1.bias": true,
|
||||
"model.language_model.layers.9.self_attn.q_norm.weight": true
|
||||
}
|
||||
},
|
||||
"methods": {
|
||||
"safetensors": {
|
||||
"cold": {
|
||||
"seconds": [
|
||||
58.55027909799992,
|
||||
59.30713190999995,
|
||||
60.17983154800004
|
||||
],
|
||||
"p50_seconds": 59.30713190999995,
|
||||
"p95_seconds": 60.17983154800004,
|
||||
"p50_throughput_gbps": 0.5739802516105188,
|
||||
"peak_gpu_bytes": 4256651264
|
||||
},
|
||||
"warm": {
|
||||
"seconds": [
|
||||
1.033367304999956,
|
||||
1.0584651120000217,
|
||||
1.1987151169998924
|
||||
],
|
||||
"p50_seconds": 1.0584651120000217,
|
||||
"p95_seconds": 1.1987151169998924,
|
||||
"p50_throughput_gbps": 32.16083563838739,
|
||||
"peak_gpu_bytes": 4256651264
|
||||
}
|
||||
},
|
||||
"safetensors_fast_gpu": {
|
||||
"cold": {
|
||||
"seconds": [
|
||||
62.305181905999916,
|
||||
58.50693893500011,
|
||||
60.62746760899995
|
||||
],
|
||||
"p50_seconds": 60.62746760899995,
|
||||
"p95_seconds": 62.305181905999916,
|
||||
"p50_throughput_gbps": 0.5614801976480164,
|
||||
"peak_gpu_bytes": 4256651264
|
||||
},
|
||||
"warm": {
|
||||
"seconds": [
|
||||
1.137218976999975,
|
||||
1.0898004420000689,
|
||||
1.1920738910000637
|
||||
],
|
||||
"p50_seconds": 1.137218976999975,
|
||||
"p95_seconds": 1.1920738910000637,
|
||||
"p50_throughput_gbps": 29.933656740236362,
|
||||
"peak_gpu_bytes": 4256651264
|
||||
}
|
||||
},
|
||||
"flashpack_bounded_direct_io": {
|
||||
"cold": {
|
||||
"seconds": [
|
||||
44.775754307999705,
|
||||
38.81784143599998,
|
||||
43.73773216100017
|
||||
],
|
||||
"p50_seconds": 43.73773216100017,
|
||||
"p95_seconds": 44.775754307999705,
|
||||
"p50_throughput_gbps": 0.7782997461938267,
|
||||
"peak_gpu_bytes": 4255121408
|
||||
},
|
||||
"warm": null,
|
||||
"sample_exact": true
|
||||
}
|
||||
},
|
||||
"probes": {
|
||||
"flashpack_8x16mib_cold_seconds": 45.7384941790001,
|
||||
"flashpack_buffered_cold_seconds": 87.244453406,
|
||||
"flashpack_buffered_warm_seconds": 0.997375596,
|
||||
"upstream_default": "failed: 2 GiB pinned staging allocation exceeded this host's available pinned-memory budget"
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,917 @@
|
||||
{
|
||||
"schema": "comfyui-vlm/optimization-matrix",
|
||||
"version": 1,
|
||||
"created_at": "2026-08-07T22:40:42.770088+00:00",
|
||||
"model": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"media": {
|
||||
"path": "/home/gokaygokay/ComfyUI_VLM_nodes/benchmarks/media/qwen-demo.jpeg",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365
|
||||
},
|
||||
"prompt": "Describe this image precisely in one sentence.",
|
||||
"model_load_seconds": 6.858,
|
||||
"environment": {
|
||||
"platform": "Linux-6.18.33.2-microsoft-standard-WSL2-x86_64-with-glibc2.35",
|
||||
"python": "3.11.14",
|
||||
"torch": "2.8.0+cu128",
|
||||
"cuda": "12.8",
|
||||
"gpu": "NVIDIA GeForce RTX 3090",
|
||||
"transformers": "5.12.1"
|
||||
},
|
||||
"runs_per_variant": 10,
|
||||
"variants": [
|
||||
{
|
||||
"id": "00",
|
||||
"label": "BF16 SDPA / dynamic cache / source resolution",
|
||||
"longest_edge": null,
|
||||
"cache": "dynamic",
|
||||
"warmups": 2,
|
||||
"processed_width": 2048,
|
||||
"processed_height": 1365,
|
||||
"quality_gate": {
|
||||
"method": "required visual concepts",
|
||||
"passed": true,
|
||||
"concepts": {
|
||||
"passed": true,
|
||||
"matched": [
|
||||
"woman",
|
||||
"golden retriever",
|
||||
"beach",
|
||||
"high-five"
|
||||
],
|
||||
"required": [
|
||||
[
|
||||
"woman",
|
||||
"person"
|
||||
],
|
||||
[
|
||||
"golden retriever",
|
||||
"dog"
|
||||
],
|
||||
[
|
||||
"beach",
|
||||
"sand"
|
||||
],
|
||||
[
|
||||
"high-five",
|
||||
"high five"
|
||||
]
|
||||
]
|
||||
},
|
||||
"exact_output_reference": null,
|
||||
"exact_output_passed": null,
|
||||
"exact_output_vs_baseline": true
|
||||
},
|
||||
"speedup_vs_baseline": {
|
||||
"ttft": 1.0,
|
||||
"e2e": 1.0,
|
||||
"throughput": 1.0
|
||||
},
|
||||
"summary": {
|
||||
"preprocess_ms_mean": 74.368,
|
||||
"ttft_ms": {
|
||||
"p50": 700.296,
|
||||
"p95": 723.148
|
||||
},
|
||||
"e2e_ms": {
|
||||
"p50": 1395.726,
|
||||
"p95": 1487.708
|
||||
},
|
||||
"output_tokens_per_second_mean": 42.32,
|
||||
"peak_vram_gib": 4.548,
|
||||
"output_tokens_mean": 31.0,
|
||||
"outputs_identical": true
|
||||
},
|
||||
"warmup_samples": [
|
||||
{
|
||||
"preprocess_ms": 119.344,
|
||||
"ttft_ms": 1411.57,
|
||||
"e2e_ms": 2117.774,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 42.481,
|
||||
"peak_vram_gib": 4.548,
|
||||
"input_tokens": 2770,
|
||||
"vision_tokens": 11008,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully giving a high-five to her.",
|
||||
"output_sha256": "7f7b9f725ce3dd1bd0e815bfcff7bf187fa2abe0d53fa7bcd7bfd612db7085da"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 74.884,
|
||||
"ttft_ms": 705.019,
|
||||
"e2e_ms": 1410.964,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 42.496,
|
||||
"peak_vram_gib": 4.548,
|
||||
"input_tokens": 2770,
|
||||
"vision_tokens": 11008,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully giving a high-five to her.",
|
||||
"output_sha256": "7f7b9f725ce3dd1bd0e815bfcff7bf187fa2abe0d53fa7bcd7bfd612db7085da"
|
||||
}
|
||||
],
|
||||
"samples": [
|
||||
{
|
||||
"preprocess_ms": 72.204,
|
||||
"ttft_ms": 701.128,
|
||||
"e2e_ms": 1389.643,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 43.572,
|
||||
"peak_vram_gib": 4.548,
|
||||
"input_tokens": 2770,
|
||||
"vision_tokens": 11008,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully giving a high-five to her.",
|
||||
"output_sha256": "7f7b9f725ce3dd1bd0e815bfcff7bf187fa2abe0d53fa7bcd7bfd612db7085da"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 72.348,
|
||||
"ttft_ms": 704.423,
|
||||
"e2e_ms": 1402.979,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 42.946,
|
||||
"peak_vram_gib": 4.548,
|
||||
"input_tokens": 2770,
|
||||
"vision_tokens": 11008,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully giving a high-five to her.",
|
||||
"output_sha256": "7f7b9f725ce3dd1bd0e815bfcff7bf187fa2abe0d53fa7bcd7bfd612db7085da"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 72.379,
|
||||
"ttft_ms": 699.464,
|
||||
"e2e_ms": 1390.29,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 43.426,
|
||||
"peak_vram_gib": 4.548,
|
||||
"input_tokens": 2770,
|
||||
"vision_tokens": 11008,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully giving a high-five to her.",
|
||||
"output_sha256": "7f7b9f725ce3dd1bd0e815bfcff7bf187fa2abe0d53fa7bcd7bfd612db7085da"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 72.929,
|
||||
"ttft_ms": 698.669,
|
||||
"e2e_ms": 1401.161,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 42.705,
|
||||
"peak_vram_gib": 4.548,
|
||||
"input_tokens": 2770,
|
||||
"vision_tokens": 11008,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully giving a high-five to her.",
|
||||
"output_sha256": "7f7b9f725ce3dd1bd0e815bfcff7bf187fa2abe0d53fa7bcd7bfd612db7085da"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 76.526,
|
||||
"ttft_ms": 731.448,
|
||||
"e2e_ms": 1537.253,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 37.23,
|
||||
"peak_vram_gib": 4.548,
|
||||
"input_tokens": 2770,
|
||||
"vision_tokens": 11008,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully giving a high-five to her.",
|
||||
"output_sha256": "7f7b9f725ce3dd1bd0e815bfcff7bf187fa2abe0d53fa7bcd7bfd612db7085da"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 76.624,
|
||||
"ttft_ms": 713.003,
|
||||
"e2e_ms": 1422.268,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 42.297,
|
||||
"peak_vram_gib": 4.548,
|
||||
"input_tokens": 2770,
|
||||
"vision_tokens": 11008,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully giving a high-five to her.",
|
||||
"output_sha256": "7f7b9f725ce3dd1bd0e815bfcff7bf187fa2abe0d53fa7bcd7bfd612db7085da"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 75.459,
|
||||
"ttft_ms": 666.823,
|
||||
"e2e_ms": 1383.653,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 41.851,
|
||||
"peak_vram_gib": 4.548,
|
||||
"input_tokens": 2770,
|
||||
"vision_tokens": 11008,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully giving a high-five to her.",
|
||||
"output_sha256": "7f7b9f725ce3dd1bd0e815bfcff7bf187fa2abe0d53fa7bcd7bfd612db7085da"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 76.597,
|
||||
"ttft_ms": 691.338,
|
||||
"e2e_ms": 1375.888,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 43.824,
|
||||
"peak_vram_gib": 4.548,
|
||||
"input_tokens": 2770,
|
||||
"vision_tokens": 11008,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully giving a high-five to her.",
|
||||
"output_sha256": "7f7b9f725ce3dd1bd0e815bfcff7bf187fa2abe0d53fa7bcd7bfd612db7085da"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 75.082,
|
||||
"ttft_ms": 711.574,
|
||||
"e2e_ms": 1427.153,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 41.924,
|
||||
"peak_vram_gib": 4.548,
|
||||
"input_tokens": 2770,
|
||||
"vision_tokens": 11008,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully giving a high-five to her.",
|
||||
"output_sha256": "7f7b9f725ce3dd1bd0e815bfcff7bf187fa2abe0d53fa7bcd7bfd612db7085da"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 73.533,
|
||||
"ttft_ms": 673.702,
|
||||
"e2e_ms": 1364.577,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 43.423,
|
||||
"peak_vram_gib": 4.548,
|
||||
"input_tokens": 2770,
|
||||
"vision_tokens": 11008,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully giving a high-five to her.",
|
||||
"output_sha256": "7f7b9f725ce3dd1bd0e815bfcff7bf187fa2abe0d53fa7bcd7bfd612db7085da"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": "01a",
|
||||
"label": "BF16 SDPA / dynamic cache / 672px edge",
|
||||
"longest_edge": 672,
|
||||
"cache": "dynamic",
|
||||
"warmups": 2,
|
||||
"processed_width": 672,
|
||||
"processed_height": 448,
|
||||
"quality_gate": {
|
||||
"method": "required visual concepts",
|
||||
"passed": true,
|
||||
"concepts": {
|
||||
"passed": true,
|
||||
"matched": [
|
||||
"woman",
|
||||
"golden retriever",
|
||||
"beach",
|
||||
"high-five"
|
||||
],
|
||||
"required": [
|
||||
[
|
||||
"woman",
|
||||
"person"
|
||||
],
|
||||
[
|
||||
"golden retriever",
|
||||
"dog"
|
||||
],
|
||||
[
|
||||
"beach",
|
||||
"sand"
|
||||
],
|
||||
[
|
||||
"high-five",
|
||||
"high five"
|
||||
]
|
||||
]
|
||||
},
|
||||
"exact_output_reference": null,
|
||||
"exact_output_passed": null,
|
||||
"exact_output_vs_baseline": false
|
||||
},
|
||||
"speedup_vs_baseline": {
|
||||
"ttft": 6.21,
|
||||
"e2e": 1.654,
|
||||
"throughput": 0.998
|
||||
},
|
||||
"summary": {
|
||||
"preprocess_ms_mean": 7.266,
|
||||
"ttft_ms": {
|
||||
"p50": 112.763,
|
||||
"p95": 122.823
|
||||
},
|
||||
"e2e_ms": {
|
||||
"p50": 843.966,
|
||||
"p95": 881.66
|
||||
},
|
||||
"output_tokens_per_second_mean": 42.225,
|
||||
"peak_vram_gib": 4.036,
|
||||
"output_tokens_mean": 32.0,
|
||||
"outputs_identical": true
|
||||
},
|
||||
"warmup_samples": [
|
||||
{
|
||||
"preprocess_ms": 6.031,
|
||||
"ttft_ms": 122.476,
|
||||
"e2e_ms": 844.441,
|
||||
"output_tokens": 32,
|
||||
"output_tokens_per_second": 42.938,
|
||||
"peak_vram_gib": 4.036,
|
||||
"input_tokens": 312,
|
||||
"vision_tokens": 1176,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "96d246f1d52b0845af007cc02f126776b655eda16d09a07f4ac1bfb4be8404f0"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 7.525,
|
||||
"ttft_ms": 113.414,
|
||||
"e2e_ms": 867.517,
|
||||
"output_tokens": 32,
|
||||
"output_tokens_per_second": 41.108,
|
||||
"peak_vram_gib": 4.036,
|
||||
"input_tokens": 312,
|
||||
"vision_tokens": 1176,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "96d246f1d52b0845af007cc02f126776b655eda16d09a07f4ac1bfb4be8404f0"
|
||||
}
|
||||
],
|
||||
"samples": [
|
||||
{
|
||||
"preprocess_ms": 8.086,
|
||||
"ttft_ms": 123.813,
|
||||
"e2e_ms": 872.379,
|
||||
"output_tokens": 32,
|
||||
"output_tokens_per_second": 41.412,
|
||||
"peak_vram_gib": 4.036,
|
||||
"input_tokens": 312,
|
||||
"vision_tokens": 1176,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "96d246f1d52b0845af007cc02f126776b655eda16d09a07f4ac1bfb4be8404f0"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 7.525,
|
||||
"ttft_ms": 114.325,
|
||||
"e2e_ms": 831.252,
|
||||
"output_tokens": 32,
|
||||
"output_tokens_per_second": 43.24,
|
||||
"peak_vram_gib": 4.036,
|
||||
"input_tokens": 312,
|
||||
"vision_tokens": 1176,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "96d246f1d52b0845af007cc02f126776b655eda16d09a07f4ac1bfb4be8404f0"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 7.52,
|
||||
"ttft_ms": 110.647,
|
||||
"e2e_ms": 889.253,
|
||||
"output_tokens": 32,
|
||||
"output_tokens_per_second": 39.815,
|
||||
"peak_vram_gib": 4.036,
|
||||
"input_tokens": 312,
|
||||
"vision_tokens": 1176,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "96d246f1d52b0845af007cc02f126776b655eda16d09a07f4ac1bfb4be8404f0"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 6.243,
|
||||
"ttft_ms": 112.581,
|
||||
"e2e_ms": 835.841,
|
||||
"output_tokens": 32,
|
||||
"output_tokens_per_second": 42.862,
|
||||
"peak_vram_gib": 4.036,
|
||||
"input_tokens": 312,
|
||||
"vision_tokens": 1176,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "96d246f1d52b0845af007cc02f126776b655eda16d09a07f4ac1bfb4be8404f0"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 6.796,
|
||||
"ttft_ms": 113.04,
|
||||
"e2e_ms": 840.013,
|
||||
"output_tokens": 32,
|
||||
"output_tokens_per_second": 42.643,
|
||||
"peak_vram_gib": 4.036,
|
||||
"input_tokens": 312,
|
||||
"vision_tokens": 1176,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "96d246f1d52b0845af007cc02f126776b655eda16d09a07f4ac1bfb4be8404f0"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 7.75,
|
||||
"ttft_ms": 110.994,
|
||||
"e2e_ms": 858.836,
|
||||
"output_tokens": 32,
|
||||
"output_tokens_per_second": 41.453,
|
||||
"peak_vram_gib": 4.036,
|
||||
"input_tokens": 312,
|
||||
"vision_tokens": 1176,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "96d246f1d52b0845af007cc02f126776b655eda16d09a07f4ac1bfb4be8404f0"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 7.667,
|
||||
"ttft_ms": 112.917,
|
||||
"e2e_ms": 847.365,
|
||||
"output_tokens": 32,
|
||||
"output_tokens_per_second": 42.209,
|
||||
"peak_vram_gib": 4.036,
|
||||
"input_tokens": 312,
|
||||
"vision_tokens": 1176,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "96d246f1d52b0845af007cc02f126776b655eda16d09a07f4ac1bfb4be8404f0"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 6.15,
|
||||
"ttft_ms": 110.293,
|
||||
"e2e_ms": 825.91,
|
||||
"output_tokens": 32,
|
||||
"output_tokens_per_second": 43.319,
|
||||
"peak_vram_gib": 4.036,
|
||||
"input_tokens": 312,
|
||||
"vision_tokens": 1176,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "96d246f1d52b0845af007cc02f126776b655eda16d09a07f4ac1bfb4be8404f0"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 7.394,
|
||||
"ttft_ms": 121.612,
|
||||
"e2e_ms": 846.696,
|
||||
"output_tokens": 32,
|
||||
"output_tokens_per_second": 42.754,
|
||||
"peak_vram_gib": 4.036,
|
||||
"input_tokens": 312,
|
||||
"vision_tokens": 1176,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "96d246f1d52b0845af007cc02f126776b655eda16d09a07f4ac1bfb4be8404f0"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 7.532,
|
||||
"ttft_ms": 112.61,
|
||||
"e2e_ms": 841.236,
|
||||
"output_tokens": 32,
|
||||
"output_tokens_per_second": 42.546,
|
||||
"peak_vram_gib": 4.036,
|
||||
"input_tokens": 312,
|
||||
"vision_tokens": 1176,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sandy beach at sunset, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "96d246f1d52b0845af007cc02f126776b655eda16d09a07f4ac1bfb4be8404f0"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": "01b",
|
||||
"label": "BF16 SDPA / dynamic cache / 448px edge",
|
||||
"longest_edge": 448,
|
||||
"cache": "dynamic",
|
||||
"warmups": 2,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299,
|
||||
"quality_gate": {
|
||||
"method": "required visual concepts",
|
||||
"passed": true,
|
||||
"concepts": {
|
||||
"passed": true,
|
||||
"matched": [
|
||||
"woman",
|
||||
"golden retriever",
|
||||
"beach",
|
||||
"high-five"
|
||||
],
|
||||
"required": [
|
||||
[
|
||||
"woman",
|
||||
"person"
|
||||
],
|
||||
[
|
||||
"golden retriever",
|
||||
"dog"
|
||||
],
|
||||
[
|
||||
"beach",
|
||||
"sand"
|
||||
],
|
||||
[
|
||||
"high-five",
|
||||
"high five"
|
||||
]
|
||||
]
|
||||
},
|
||||
"exact_output_reference": null,
|
||||
"exact_output_passed": null,
|
||||
"exact_output_vs_baseline": false
|
||||
},
|
||||
"speedup_vs_baseline": {
|
||||
"ttft": 7.942,
|
||||
"e2e": 1.803,
|
||||
"throughput": 1.033
|
||||
},
|
||||
"summary": {
|
||||
"preprocess_ms_mean": 4.583,
|
||||
"ttft_ms": {
|
||||
"p50": 88.172,
|
||||
"p95": 90.227
|
||||
},
|
||||
"e2e_ms": {
|
||||
"p50": 774.062,
|
||||
"p95": 780.506
|
||||
},
|
||||
"output_tokens_per_second_mean": 43.707,
|
||||
"peak_vram_gib": 4.001,
|
||||
"output_tokens_mean": 31.0,
|
||||
"outputs_identical": true
|
||||
},
|
||||
"warmup_samples": [
|
||||
{
|
||||
"preprocess_ms": 3.98,
|
||||
"ttft_ms": 88.636,
|
||||
"e2e_ms": 768.672,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 44.115,
|
||||
"peak_vram_gib": 4.001,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.299,
|
||||
"ttft_ms": 88.223,
|
||||
"e2e_ms": 773.967,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 43.748,
|
||||
"peak_vram_gib": 4.001,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
}
|
||||
],
|
||||
"samples": [
|
||||
{
|
||||
"preprocess_ms": 4.915,
|
||||
"ttft_ms": 89.425,
|
||||
"e2e_ms": 778.012,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 43.567,
|
||||
"peak_vram_gib": 4.001,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.91,
|
||||
"ttft_ms": 90.767,
|
||||
"e2e_ms": 773.458,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 43.944,
|
||||
"peak_vram_gib": 4.001,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.475,
|
||||
"ttft_ms": 87.596,
|
||||
"e2e_ms": 780.921,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 43.27,
|
||||
"peak_vram_gib": 4.001,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 5.156,
|
||||
"ttft_ms": 89.35,
|
||||
"e2e_ms": 772.663,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 43.904,
|
||||
"peak_vram_gib": 4.001,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.618,
|
||||
"ttft_ms": 87.633,
|
||||
"e2e_ms": 773.253,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 43.756,
|
||||
"peak_vram_gib": 4.001,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.432,
|
||||
"ttft_ms": 88.058,
|
||||
"e2e_ms": 779.999,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 43.356,
|
||||
"peak_vram_gib": 4.001,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.676,
|
||||
"ttft_ms": 89.566,
|
||||
"e2e_ms": 768.915,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 44.16,
|
||||
"peak_vram_gib": 4.001,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.846,
|
||||
"ttft_ms": 87.046,
|
||||
"e2e_ms": 778.431,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 43.391,
|
||||
"peak_vram_gib": 4.001,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.991,
|
||||
"ttft_ms": 88.103,
|
||||
"e2e_ms": 774.665,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 43.696,
|
||||
"peak_vram_gib": 4.001,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.815,
|
||||
"ttft_ms": 88.242,
|
||||
"e2e_ms": 769.596,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 44.03,
|
||||
"peak_vram_gib": 4.001,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
}
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": "02",
|
||||
"label": "BF16 SDPA / static compiled cache / 448px edge",
|
||||
"longest_edge": 448,
|
||||
"cache": "static",
|
||||
"warmups": 6,
|
||||
"exact_reference": "01b",
|
||||
"processed_width": 448,
|
||||
"processed_height": 299,
|
||||
"quality_gate": {
|
||||
"method": "required visual concepts plus byte-identical output against variant 01b",
|
||||
"passed": true,
|
||||
"concepts": {
|
||||
"passed": true,
|
||||
"matched": [
|
||||
"woman",
|
||||
"golden retriever",
|
||||
"beach",
|
||||
"high-five"
|
||||
],
|
||||
"required": [
|
||||
[
|
||||
"woman",
|
||||
"person"
|
||||
],
|
||||
[
|
||||
"golden retriever",
|
||||
"dog"
|
||||
],
|
||||
[
|
||||
"beach",
|
||||
"sand"
|
||||
],
|
||||
[
|
||||
"high-five",
|
||||
"high five"
|
||||
]
|
||||
]
|
||||
},
|
||||
"exact_output_reference": "01b",
|
||||
"exact_output_passed": true,
|
||||
"exact_output_vs_baseline": false
|
||||
},
|
||||
"speedup_vs_baseline": {
|
||||
"ttft": 9.142,
|
||||
"e2e": 4.811,
|
||||
"throughput": 3.295
|
||||
},
|
||||
"summary": {
|
||||
"preprocess_ms_mean": 4.24,
|
||||
"ttft_ms": {
|
||||
"p50": 76.6,
|
||||
"p95": 77.349
|
||||
},
|
||||
"e2e_ms": {
|
||||
"p50": 290.124,
|
||||
"p95": 299.671
|
||||
},
|
||||
"output_tokens_per_second_mean": 139.435,
|
||||
"peak_vram_gib": 4.023,
|
||||
"output_tokens_mean": 31.0,
|
||||
"outputs_identical": true
|
||||
},
|
||||
"warmup_samples": [
|
||||
{
|
||||
"preprocess_ms": 4.676,
|
||||
"ttft_ms": 5838.639,
|
||||
"e2e_ms": 6436.632,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 50.168,
|
||||
"peak_vram_gib": 4.011,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.922,
|
||||
"ttft_ms": 79.28,
|
||||
"e2e_ms": 294.627,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 139.31,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.893,
|
||||
"ttft_ms": 76.419,
|
||||
"e2e_ms": 292.685,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 138.718,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.068,
|
||||
"ttft_ms": 76.42,
|
||||
"e2e_ms": 287.574,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 142.076,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.804,
|
||||
"ttft_ms": 73.609,
|
||||
"e2e_ms": 289.638,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 138.871,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.888,
|
||||
"ttft_ms": 77.168,
|
||||
"e2e_ms": 292.967,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 139.018,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
}
|
||||
],
|
||||
"samples": [
|
||||
{
|
||||
"preprocess_ms": 4.199,
|
||||
"ttft_ms": 73.284,
|
||||
"e2e_ms": 289.897,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 138.496,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.649,
|
||||
"ttft_ms": 76.752,
|
||||
"e2e_ms": 288.657,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 141.573,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.599,
|
||||
"ttft_ms": 76.872,
|
||||
"e2e_ms": 288.993,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 141.429,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.903,
|
||||
"ttft_ms": 76.448,
|
||||
"e2e_ms": 287.537,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 142.121,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.784,
|
||||
"ttft_ms": 76.333,
|
||||
"e2e_ms": 303.535,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 132.041,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.625,
|
||||
"ttft_ms": 77.362,
|
||||
"e2e_ms": 294.949,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 137.876,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.001,
|
||||
"ttft_ms": 75.874,
|
||||
"e2e_ms": 290.573,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 139.731,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.878,
|
||||
"ttft_ms": 75.599,
|
||||
"e2e_ms": 287.892,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 141.315,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.702,
|
||||
"ttft_ms": 77.109,
|
||||
"e2e_ms": 290.35,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 140.686,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 5.057,
|
||||
"ttft_ms": 77.332,
|
||||
"e2e_ms": 293.032,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 139.082,
|
||||
"peak_vram_gib": 4.023,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
}
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,181 @@
|
||||
{
|
||||
"schema": "comfyui-vlm/transformers-benchmark",
|
||||
"version": 1,
|
||||
"created_at": "2026-08-07T23:06:56.398807+00:00",
|
||||
"label": "qwen3-vl-2b-sdpa-static-edge448-tf32",
|
||||
"model": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"git_commit": "858a4a4998e68bd99b26a12831e861be49904564",
|
||||
"git_dirty": true,
|
||||
"media": {
|
||||
"path": "/home/gokaygokay/ComfyUI_VLM_nodes/benchmarks/media/qwen-demo.jpeg",
|
||||
"sha256": "9eeaa87013b4e800930e8a411b58ff9e2fd5383906b1a022f4a712720af34cc2",
|
||||
"source_width": 2048,
|
||||
"source_height": 1365,
|
||||
"processed_width": 448,
|
||||
"processed_height": 299
|
||||
},
|
||||
"environment": {
|
||||
"platform": "Linux-6.18.33.2-microsoft-standard-WSL2-x86_64-with-glibc2.35",
|
||||
"python": "3.11.14",
|
||||
"torch": "2.8.0+cu128",
|
||||
"cuda": "12.8",
|
||||
"gpu": "NVIDIA GeForce RTX 3090",
|
||||
"transformers": "5.12.1",
|
||||
"flash_attn": null
|
||||
},
|
||||
"settings": {
|
||||
"attention": "sdpa",
|
||||
"cache": "static",
|
||||
"disable_compile": false,
|
||||
"min_pixels": null,
|
||||
"max_pixels": null,
|
||||
"longest_edge": 448,
|
||||
"max_new_tokens": 96,
|
||||
"warmups": 6,
|
||||
"runs": 10,
|
||||
"float32_matmul_precision": "high"
|
||||
},
|
||||
"model_load_seconds": 83.958,
|
||||
"quality_gate": {
|
||||
"method": "byte-identical output SHA-256",
|
||||
"reference_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1",
|
||||
"passed": true
|
||||
},
|
||||
"summary": {
|
||||
"preprocess_ms_mean": 4.357,
|
||||
"ttft_ms": {
|
||||
"p50": 74.256,
|
||||
"p95": 79.529
|
||||
},
|
||||
"e2e_ms": {
|
||||
"p50": 274.547,
|
||||
"p95": 289.619
|
||||
},
|
||||
"output_tokens_per_second_mean": 149.167,
|
||||
"peak_vram_gib": 4.025,
|
||||
"output_tokens_mean": 31.0,
|
||||
"outputs_identical": true
|
||||
},
|
||||
"samples": [
|
||||
{
|
||||
"preprocess_ms": 5.029,
|
||||
"ttft_ms": 79.329,
|
||||
"e2e_ms": 278.01,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 150.996,
|
||||
"peak_vram_gib": 4.025,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.893,
|
||||
"ttft_ms": 79.693,
|
||||
"e2e_ms": 276.153,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 152.703,
|
||||
"peak_vram_gib": 4.025,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.754,
|
||||
"ttft_ms": 71.308,
|
||||
"e2e_ms": 269.219,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 151.584,
|
||||
"peak_vram_gib": 4.025,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.838,
|
||||
"ttft_ms": 74.473,
|
||||
"e2e_ms": 272.941,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 151.158,
|
||||
"peak_vram_gib": 4.025,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.331,
|
||||
"ttft_ms": 74.039,
|
||||
"e2e_ms": 281.754,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 144.429,
|
||||
"peak_vram_gib": 4.025,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.426,
|
||||
"ttft_ms": 73.694,
|
||||
"e2e_ms": 272.792,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 150.68,
|
||||
"peak_vram_gib": 4.025,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 3.908,
|
||||
"ttft_ms": 72.445,
|
||||
"e2e_ms": 269.177,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 152.492,
|
||||
"peak_vram_gib": 4.025,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.856,
|
||||
"ttft_ms": 74.703,
|
||||
"e2e_ms": 276.675,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 148.536,
|
||||
"peak_vram_gib": 4.025,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.905,
|
||||
"ttft_ms": 78.645,
|
||||
"e2e_ms": 296.054,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 137.989,
|
||||
"peak_vram_gib": 4.025,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.63,
|
||||
"ttft_ms": 73.816,
|
||||
"e2e_ms": 272.358,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 151.101,
|
||||
"peak_vram_gib": 4.025,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,247 @@
|
||||
{
|
||||
"schema": "comfyui-vlm/tensorrt-vision-probe",
|
||||
"version": 1,
|
||||
"created_at": "2026-08-08T00:49:06.960727+00:00",
|
||||
"model": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"media": {
|
||||
"path": "/home/gokaygokay/ComfyUI_VLM_nodes/benchmarks/media/qwen-demo.jpeg",
|
||||
"processed_size": [
|
||||
448,
|
||||
299
|
||||
],
|
||||
"pixel_values_shape": [
|
||||
504,
|
||||
1536
|
||||
],
|
||||
"image_grid_thw": [
|
||||
[
|
||||
1,
|
||||
18,
|
||||
28
|
||||
]
|
||||
]
|
||||
},
|
||||
"environment": {
|
||||
"platform": "Linux-6.18.33.2-microsoft-standard-WSL2-x86_64-with-glibc2.35",
|
||||
"python": "3.11.14",
|
||||
"torch": "2.9.0+cu128",
|
||||
"cuda": "12.8",
|
||||
"torch_tensorrt": "2.9.0+cu128",
|
||||
"tensorrt": "10.13.3.9.post1",
|
||||
"transformers": "5.12.1",
|
||||
"gpu": "NVIDIA GeForce RTX 3090"
|
||||
},
|
||||
"configuration": {
|
||||
"precision": "bfloat16",
|
||||
"min_block_size": 5,
|
||||
"optimization_level": 3,
|
||||
"require_full_compilation": false,
|
||||
"warmups": 3,
|
||||
"runs": 10,
|
||||
"generation_warmups": 1,
|
||||
"generation_runs": 3
|
||||
},
|
||||
"model_load_seconds": 78.171,
|
||||
"compile_seconds": 98.07,
|
||||
"coverage": {
|
||||
"available": true,
|
||||
"graph_nodes": 8,
|
||||
"call_modules": [
|
||||
"_run_on_acc_0"
|
||||
],
|
||||
"tensorrt_engine_partitions": 1,
|
||||
"pytorch_fallback_partitions": 0
|
||||
},
|
||||
"fidelity": [
|
||||
{
|
||||
"output_index": 0,
|
||||
"shape": [
|
||||
504,
|
||||
1024
|
||||
],
|
||||
"max_absolute_error": 1380.0,
|
||||
"mean_absolute_error": 0.563834547996521,
|
||||
"cosine_similarity": 0.9949914216995239
|
||||
},
|
||||
{
|
||||
"output_index": 1,
|
||||
"shape": [
|
||||
126,
|
||||
2048
|
||||
],
|
||||
"max_absolute_error": 2.375,
|
||||
"mean_absolute_error": 0.025903113186359406,
|
||||
"cosine_similarity": 0.9966588020324707
|
||||
},
|
||||
{
|
||||
"output_index": 2,
|
||||
"shape": [
|
||||
126,
|
||||
2048
|
||||
],
|
||||
"max_absolute_error": 0.09375,
|
||||
"mean_absolute_error": 0.004035853315144777,
|
||||
"cosine_similarity": 0.9999096393585205
|
||||
},
|
||||
{
|
||||
"output_index": 3,
|
||||
"shape": [
|
||||
126,
|
||||
2048
|
||||
],
|
||||
"max_absolute_error": 0.978515625,
|
||||
"mean_absolute_error": 0.009971227496862411,
|
||||
"cosine_similarity": 0.9982407093048096
|
||||
},
|
||||
{
|
||||
"output_index": 4,
|
||||
"shape": [
|
||||
126,
|
||||
2048
|
||||
],
|
||||
"max_absolute_error": 3.34375,
|
||||
"mean_absolute_error": 0.018642043694853783,
|
||||
"cosine_similarity": 0.998470664024353
|
||||
}
|
||||
],
|
||||
"latency_ms": {
|
||||
"eager_samples": [
|
||||
2391.378,
|
||||
2382.472,
|
||||
2386.845,
|
||||
2408.021,
|
||||
2382.034,
|
||||
2381.989,
|
||||
2431.839,
|
||||
2419.309,
|
||||
2382.089,
|
||||
2383.834
|
||||
],
|
||||
"tensorrt_samples": [
|
||||
9.526,
|
||||
8.409,
|
||||
8.817,
|
||||
9.337,
|
||||
8.556,
|
||||
9.596,
|
||||
8.549,
|
||||
9.892,
|
||||
8.632,
|
||||
9.572
|
||||
],
|
||||
"eager_median": 2385.339,
|
||||
"tensorrt_median": 9.077,
|
||||
"speedup": 262.779
|
||||
},
|
||||
"generation": {
|
||||
"eager": {
|
||||
"preprocess_ms_mean": 4.546,
|
||||
"ttft_ms": {
|
||||
"p50": 2452.88,
|
||||
"p95": 2464.33
|
||||
},
|
||||
"e2e_ms": {
|
||||
"p50": 2660.594,
|
||||
"p95": 2674.669
|
||||
},
|
||||
"output_tokens_per_second_mean": 143.283,
|
||||
"peak_vram_gib": 4.028,
|
||||
"output_tokens_mean": 31.0,
|
||||
"outputs_identical": true
|
||||
},
|
||||
"tensorrt": {
|
||||
"preprocess_ms_mean": 6.582,
|
||||
"ttft_ms": {
|
||||
"p50": 61.388,
|
||||
"p95": 62.364
|
||||
},
|
||||
"e2e_ms": {
|
||||
"p50": 273.449,
|
||||
"p95": 274.016
|
||||
},
|
||||
"output_tokens_per_second_mean": 142.09,
|
||||
"peak_vram_gib": 4.024,
|
||||
"output_tokens_mean": 31.0,
|
||||
"outputs_identical": true
|
||||
},
|
||||
"exact_output_match": true,
|
||||
"eager_output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"tensorrt_output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"eager_samples": [
|
||||
{
|
||||
"preprocess_ms": 4.702,
|
||||
"ttft_ms": 2465.602,
|
||||
"e2e_ms": 2676.233,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 142.429,
|
||||
"peak_vram_gib": 4.028,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.443,
|
||||
"ttft_ms": 2452.88,
|
||||
"e2e_ms": 2660.594,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 144.429,
|
||||
"peak_vram_gib": 4.028,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 4.493,
|
||||
"ttft_ms": 2446.741,
|
||||
"e2e_ms": 2656.543,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 142.992,
|
||||
"peak_vram_gib": 4.028,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
}
|
||||
],
|
||||
"tensorrt_samples": [
|
||||
{
|
||||
"preprocess_ms": 6.038,
|
||||
"ttft_ms": 60.673,
|
||||
"e2e_ms": 270.425,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 143.026,
|
||||
"peak_vram_gib": 4.024,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 6.937,
|
||||
"ttft_ms": 62.472,
|
||||
"e2e_ms": 273.449,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 142.196,
|
||||
"peak_vram_gib": 4.024,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
},
|
||||
{
|
||||
"preprocess_ms": 6.772,
|
||||
"ttft_ms": 61.388,
|
||||
"e2e_ms": 274.079,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 141.049,
|
||||
"peak_vram_gib": 4.024,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,189 @@
|
||||
{
|
||||
"schema": "comfyui-vlm/tensorrt-vision-probe",
|
||||
"version": 1,
|
||||
"created_at": "2026-08-08T07:02:36.436372+00:00",
|
||||
"model": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"media": {
|
||||
"path": "/home/gokaygokay/ComfyUI_VLM_nodes/benchmarks/media/qwen-demo.jpeg",
|
||||
"processed_size": [
|
||||
448,
|
||||
299
|
||||
],
|
||||
"pixel_values_shape": [
|
||||
504,
|
||||
1536
|
||||
],
|
||||
"image_grid_thw": [
|
||||
[
|
||||
1,
|
||||
18,
|
||||
28
|
||||
]
|
||||
]
|
||||
},
|
||||
"environment": {
|
||||
"platform": "Linux-6.18.33.2-microsoft-standard-WSL2-x86_64-with-glibc2.35",
|
||||
"python": "3.11.14",
|
||||
"torch": "2.9.0+cu128",
|
||||
"cuda": "12.8",
|
||||
"torch_tensorrt": "2.9.0+cu128",
|
||||
"tensorrt": "10.13.3.9.post1",
|
||||
"transformers": "5.12.1",
|
||||
"gpu": "NVIDIA GeForce RTX 3090"
|
||||
},
|
||||
"configuration": {
|
||||
"precision": "bfloat16",
|
||||
"min_block_size": 5,
|
||||
"optimization_level": 3,
|
||||
"require_full_compilation": true,
|
||||
"warmups": 2,
|
||||
"runs": 5,
|
||||
"generation_warmups": 0,
|
||||
"generation_runs": 1
|
||||
},
|
||||
"model_load_seconds": 80.059,
|
||||
"compile_seconds": 96.692,
|
||||
"coverage": {
|
||||
"available": true,
|
||||
"graph_nodes": 8,
|
||||
"call_modules": [
|
||||
"_run_on_acc_0"
|
||||
],
|
||||
"tensorrt_engine_partitions": 1,
|
||||
"pytorch_fallback_partitions": 0
|
||||
},
|
||||
"fidelity": [
|
||||
{
|
||||
"output_index": 0,
|
||||
"shape": [
|
||||
504,
|
||||
1024
|
||||
],
|
||||
"max_absolute_error": 1380.0,
|
||||
"mean_absolute_error": 0.563834547996521,
|
||||
"cosine_similarity": 0.9949914216995239
|
||||
},
|
||||
{
|
||||
"output_index": 1,
|
||||
"shape": [
|
||||
126,
|
||||
2048
|
||||
],
|
||||
"max_absolute_error": 2.375,
|
||||
"mean_absolute_error": 0.025903113186359406,
|
||||
"cosine_similarity": 0.9966588020324707
|
||||
},
|
||||
{
|
||||
"output_index": 2,
|
||||
"shape": [
|
||||
126,
|
||||
2048
|
||||
],
|
||||
"max_absolute_error": 0.09375,
|
||||
"mean_absolute_error": 0.004035853315144777,
|
||||
"cosine_similarity": 0.9999096393585205
|
||||
},
|
||||
{
|
||||
"output_index": 3,
|
||||
"shape": [
|
||||
126,
|
||||
2048
|
||||
],
|
||||
"max_absolute_error": 0.978515625,
|
||||
"mean_absolute_error": 0.009971227496862411,
|
||||
"cosine_similarity": 0.9982407093048096
|
||||
},
|
||||
{
|
||||
"output_index": 4,
|
||||
"shape": [
|
||||
126,
|
||||
2048
|
||||
],
|
||||
"max_absolute_error": 3.34375,
|
||||
"mean_absolute_error": 0.018642043694853783,
|
||||
"cosine_similarity": 0.998470664024353
|
||||
}
|
||||
],
|
||||
"latency_ms": {
|
||||
"eager_samples": [
|
||||
2371.396,
|
||||
2388.794,
|
||||
2374.26,
|
||||
2374.196,
|
||||
2362.955
|
||||
],
|
||||
"tensorrt_samples": [
|
||||
8.405,
|
||||
9.066,
|
||||
8.388,
|
||||
9.738,
|
||||
8.271
|
||||
],
|
||||
"eager_median": 2374.196,
|
||||
"tensorrt_median": 8.405,
|
||||
"speedup": 282.491
|
||||
},
|
||||
"generation": {
|
||||
"eager": {
|
||||
"preprocess_ms_mean": 6.771,
|
||||
"ttft_ms": {
|
||||
"p50": 42960.862,
|
||||
"p95": 42960.862
|
||||
},
|
||||
"e2e_ms": {
|
||||
"p50": 43196.275,
|
||||
"p95": 43196.275
|
||||
},
|
||||
"output_tokens_per_second_mean": 127.436,
|
||||
"peak_vram_gib": 4.025,
|
||||
"output_tokens_mean": 31.0,
|
||||
"outputs_identical": true
|
||||
},
|
||||
"tensorrt": {
|
||||
"preprocess_ms_mean": 8.081,
|
||||
"ttft_ms": {
|
||||
"p50": 325.253,
|
||||
"p95": 325.253
|
||||
},
|
||||
"e2e_ms": {
|
||||
"p50": 552.777,
|
||||
"p95": 552.777
|
||||
},
|
||||
"output_tokens_per_second_mean": 131.854,
|
||||
"peak_vram_gib": 4.022,
|
||||
"output_tokens_mean": 31.0,
|
||||
"outputs_identical": true
|
||||
},
|
||||
"exact_output_match": true,
|
||||
"eager_output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"tensorrt_output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"eager_samples": [
|
||||
{
|
||||
"preprocess_ms": 6.771,
|
||||
"ttft_ms": 42960.862,
|
||||
"e2e_ms": 43196.275,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 127.436,
|
||||
"peak_vram_gib": 4.025,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
}
|
||||
],
|
||||
"tensorrt_samples": [
|
||||
{
|
||||
"preprocess_ms": 8.081,
|
||||
"ttft_ms": 325.253,
|
||||
"e2e_ms": 552.777,
|
||||
"output_tokens": 31,
|
||||
"output_tokens_per_second": 131.854,
|
||||
"peak_vram_gib": 4.022,
|
||||
"input_tokens": 144,
|
||||
"vision_tokens": 504,
|
||||
"output": "A woman and her golden retriever share a joyful moment on a sunlit beach, with the dog playfully reaching out to give a high-five.",
|
||||
"output_sha256": "7b1c4202212d7ecbb5c90cb79ac7d6395cf487e97fdd7980f0c43687104184c1"
|
||||
}
|
||||
]
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,5 @@
|
||||
"""Process bootstrap for the Qwen3-VL TensorRT/SGLang benchmark."""
|
||||
|
||||
from qwen3_vl_sglang_tensorrt_bridge import install_bridge
|
||||
|
||||
install_bridge()
|
||||
@@ -0,0 +1,40 @@
|
||||
# See https://help.github.com/articles/ignoring-files/ for more about ignoring files.
|
||||
|
||||
# dependencies
|
||||
/node_modules
|
||||
/.pnp
|
||||
.pnp.*
|
||||
.yarn/*
|
||||
!.yarn/patches
|
||||
!.yarn/plugins
|
||||
!.yarn/releases
|
||||
!.yarn/versions
|
||||
|
||||
# testing
|
||||
/coverage
|
||||
|
||||
# next.js
|
||||
/.next/
|
||||
/.vinext/
|
||||
/out/
|
||||
|
||||
# misc
|
||||
.DS_Store
|
||||
*.pem
|
||||
|
||||
# debug
|
||||
npm-debug.log*
|
||||
yarn-debug.log*
|
||||
yarn-error.log*
|
||||
.pnpm-debug.log*
|
||||
|
||||
# env files (can opt-in for committing if needed)
|
||||
.env*
|
||||
|
||||
# vercel
|
||||
.vercel
|
||||
|
||||
/dist/
|
||||
/.wrangler/
|
||||
/outputs/
|
||||
/work/
|
||||
@@ -0,0 +1,5 @@
|
||||
{
|
||||
"project_id": "appgprj_6a7654db28d48191858ee067884b6d34",
|
||||
"d1": null,
|
||||
"r2": null
|
||||
}
|
||||
@@ -0,0 +1,100 @@
|
||||
# vinext-starter
|
||||
|
||||
A clean full-stack starter running on
|
||||
[vinext](https://github.com/cloudflare/vinext), with optional Cloudflare D1 and
|
||||
Drizzle support.
|
||||
|
||||
## Prerequisites
|
||||
|
||||
- Node.js `>=22.13.0`
|
||||
|
||||
## Quick Start
|
||||
|
||||
```bash
|
||||
npm install
|
||||
npm run dev
|
||||
npm run build
|
||||
```
|
||||
|
||||
This starter does not use `wrangler.jsonc`.
|
||||
|
||||
## Included Shape
|
||||
|
||||
- edit site code under `app/`
|
||||
- `.openai/hosting.json` declares optional Sites D1 and R2 bindings
|
||||
- `vite.config.ts` simulates declared bindings for local development
|
||||
- `db/schema.ts` starts intentionally empty
|
||||
- `examples/d1/` contains an optional D1 example surface
|
||||
- `drizzle.config.ts` supports local migration generation when needed
|
||||
|
||||
## Workspace Auth Headers
|
||||
|
||||
Signed-in visitors receive both `oai-authenticated-user-id` and `oai-authenticated-user-email`. Private Sites require every visitor to sign in; public Sites may also have anonymous visitors, for whom neither header is present.
|
||||
|
||||
The user ID is stable for the same user on the same Site and different across Sites. Email and name are intended for display or contact purposes.
|
||||
|
||||
SIWC-authenticated workspace sites may also receive
|
||||
`oai-authenticated-user-full-name` when the user's SIWC profile has a non-empty
|
||||
`name` claim. The full-name value is percent-encoded UTF-8 and is accompanied by
|
||||
`oai-authenticated-user-full-name-encoding: percent-encoded-utf-8`.
|
||||
|
||||
Treat the full name as optional and fall back to email when it is absent:
|
||||
|
||||
```tsx
|
||||
import { headers } from "next/headers";
|
||||
|
||||
export default async function Home() {
|
||||
const requestHeaders = await headers();
|
||||
const userId = requestHeaders.get("oai-authenticated-user-id");
|
||||
const email = requestHeaders.get("oai-authenticated-user-email");
|
||||
const encodedFullName = requestHeaders.get("oai-authenticated-user-full-name");
|
||||
const fullName =
|
||||
encodedFullName &&
|
||||
requestHeaders.get("oai-authenticated-user-full-name-encoding") ===
|
||||
"percent-encoded-utf-8"
|
||||
? decodeURIComponent(encodedFullName)
|
||||
: null;
|
||||
|
||||
const displayName = fullName ?? email;
|
||||
// ...
|
||||
}
|
||||
```
|
||||
|
||||
## Optional Dispatch-Owned ChatGPT Sign-In
|
||||
|
||||
Import the ready-to-use helpers from `app/chatgpt-auth.ts` when the site needs
|
||||
optional or required ChatGPT sign-in:
|
||||
|
||||
- Use `getChatGPTUser()` for optional signed-in UI.
|
||||
- Use `requireChatGPTUser(returnTo)` for server-rendered pages that should send
|
||||
anonymous visitors through Sign in with ChatGPT.
|
||||
- Use `chatGPTSignInPath(returnTo)` and `chatGPTSignOutPath(returnTo)` for
|
||||
browser links or actions.
|
||||
- Pass a same-origin relative `returnTo` path for the destination after sign-in
|
||||
or sign-out. The helper validates and safely encodes it.
|
||||
- Mark protected pages with `export const dynamic = "force-dynamic"` because
|
||||
they depend on per-request identity headers.
|
||||
|
||||
Dispatch owns `/signin-with-chatgpt`, `/signout-with-chatgpt`, `/callback`, the
|
||||
OAuth cookies, and identity header injection. Do not implement app routes for
|
||||
those reserved paths. Routes that do not import and call the helper remain
|
||||
anonymous-compatible.
|
||||
|
||||
SIWC establishes identity only; it does not prove workspace membership. Use the
|
||||
Sites hosting platform's access policy controls for workspace-wide restrictions,
|
||||
or enforce explicit server-side membership or allowlist checks.
|
||||
|
||||
Use SIWC for account pages, user-specific dashboards, saved records, and write
|
||||
actions tied to the current ChatGPT user. Leave public content anonymous.
|
||||
|
||||
## Useful Commands
|
||||
|
||||
- `npm run dev`: start local development
|
||||
- `npm run build`: verify the vinext build output
|
||||
- `npm test`: build the starter and verify its rendered loading skeleton
|
||||
- `npm run db:generate`: generate Drizzle migrations after schema changes
|
||||
|
||||
## Learn More
|
||||
|
||||
- [vinext Documentation](https://github.com/cloudflare/vinext)
|
||||
- [Drizzle D1 Guide](https://orm.drizzle.team/docs/get-started/d1-new)
|
||||
@@ -0,0 +1,90 @@
|
||||
import { headers } from "next/headers";
|
||||
import { redirect } from "next/navigation";
|
||||
|
||||
export type ChatGPTUser = {
|
||||
userId: string;
|
||||
displayName: string;
|
||||
email: string;
|
||||
fullName: string | null;
|
||||
};
|
||||
|
||||
const USER_ID_HEADER = "oai-authenticated-user-id";
|
||||
const USER_EMAIL_HEADER = "oai-authenticated-user-email";
|
||||
const USER_FULL_NAME_HEADER = "oai-authenticated-user-full-name";
|
||||
const USER_FULL_NAME_ENCODING_HEADER =
|
||||
"oai-authenticated-user-full-name-encoding";
|
||||
const PERCENT_ENCODED_UTF8 = "percent-encoded-utf-8";
|
||||
const SIGN_IN_PATH = "/signin-with-chatgpt";
|
||||
const SIGN_OUT_PATH = "/signout-with-chatgpt";
|
||||
const CALLBACK_PATH = "/callback";
|
||||
|
||||
export async function getChatGPTUser(): Promise<ChatGPTUser | null> {
|
||||
const requestHeaders = await headers();
|
||||
const userId = requestHeaders.get(USER_ID_HEADER);
|
||||
const email = requestHeaders.get(USER_EMAIL_HEADER);
|
||||
if (!userId || !email) return null;
|
||||
|
||||
const encodedFullName = requestHeaders.get(USER_FULL_NAME_HEADER);
|
||||
const fullName =
|
||||
encodedFullName &&
|
||||
requestHeaders.get(USER_FULL_NAME_ENCODING_HEADER) === PERCENT_ENCODED_UTF8
|
||||
? safeDecodeURIComponent(encodedFullName)
|
||||
: null;
|
||||
|
||||
return {
|
||||
userId,
|
||||
displayName: fullName ?? email,
|
||||
email,
|
||||
fullName,
|
||||
};
|
||||
}
|
||||
|
||||
export async function requireChatGPTUser(
|
||||
returnTo: string,
|
||||
): Promise<ChatGPTUser> {
|
||||
const user = await getChatGPTUser();
|
||||
if (user) return user;
|
||||
|
||||
redirect(chatGPTSignInPath(returnTo));
|
||||
}
|
||||
|
||||
export function chatGPTSignInPath(returnTo: string): string {
|
||||
const safeReturnTo = safeRelativeReturnPath(returnTo);
|
||||
return `${SIGN_IN_PATH}?return_to=${encodeURIComponent(safeReturnTo)}`;
|
||||
}
|
||||
|
||||
export function chatGPTSignOutPath(returnTo = "/"): string {
|
||||
const safeReturnTo = safeRelativeReturnPath(returnTo);
|
||||
return `${SIGN_OUT_PATH}?return_to=${encodeURIComponent(safeReturnTo)}`;
|
||||
}
|
||||
|
||||
function safeRelativeReturnPath(value: string): string {
|
||||
if (!value.startsWith("/") || value.startsWith("//")) return "/";
|
||||
|
||||
let url: URL;
|
||||
try {
|
||||
url = new URL(value, "https://app.local");
|
||||
} catch {
|
||||
return "/";
|
||||
}
|
||||
if (url.origin !== "https://app.local") return "/";
|
||||
if (isReservedAuthPath(url.pathname)) return "/";
|
||||
|
||||
return `${url.pathname}${url.search}${url.hash}`;
|
||||
}
|
||||
|
||||
function isReservedAuthPath(pathname: string): boolean {
|
||||
return (
|
||||
pathname === SIGN_IN_PATH ||
|
||||
pathname === SIGN_OUT_PATH ||
|
||||
pathname === CALLBACK_PATH
|
||||
);
|
||||
}
|
||||
|
||||
function safeDecodeURIComponent(value: string): string | null {
|
||||
try {
|
||||
return decodeURIComponent(value);
|
||||
} catch {
|
||||
return null;
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,157 @@
|
||||
@import "tailwindcss";
|
||||
|
||||
:root { --ink:#11130f; --paper:#f3f0e7; --lime:#c8ff36; --orange:#ff6b35; --muted:#706f68; --line:#d3d0c5; }
|
||||
* { box-sizing:border-box; }
|
||||
html { scroll-behavior:smooth; }
|
||||
body { margin:0; background:var(--paper); color:var(--ink); font-family:var(--font-geist-sans), Arial, sans-serif; }
|
||||
a { color:inherit; text-decoration:none; }
|
||||
.topbar { height:76px; padding:0 4.5vw; display:flex; align-items:center; justify-content:space-between; border-bottom:1px solid var(--line); position:sticky; top:0; z-index:10; background:rgba(243,240,231,.92); backdrop-filter:blur(16px); }
|
||||
.brand { display:flex; align-items:center; gap:11px; font-weight:760; letter-spacing:-.02em; }
|
||||
.brand-mark { display:grid; place-items:center; width:34px; height:34px; background:var(--ink); color:var(--lime); font:700 11px var(--font-geist-mono); transform:rotate(-3deg); }
|
||||
nav { display:flex; gap:34px; color:#55564f; font-size:13px; }
|
||||
nav a:hover { color:var(--ink); }
|
||||
.repo-link { font:650 12px var(--font-geist-mono); border-bottom:1px solid var(--ink); padding-bottom:3px; }
|
||||
.hero { min-height:690px; padding:72px 6vw 70px; display:grid; grid-template-columns:1.18fr .82fr; gap:7vw; align-items:center; overflow:hidden; background-image:linear-gradient(rgba(17,19,15,.035) 1px,transparent 1px),linear-gradient(90deg,rgba(17,19,15,.035) 1px,transparent 1px); background-size:42px 42px; }
|
||||
.eyebrow { font:700 11px/1.2 var(--font-geist-mono); letter-spacing:.12em; text-transform:uppercase; display:flex; align-items:center; gap:9px; }
|
||||
.eyebrow.light { color:var(--lime); }
|
||||
.live-dot { width:8px; height:8px; border-radius:99px; background:var(--orange); box-shadow:0 0 0 5px rgba(255,107,53,.15); }
|
||||
h1 { font-size:clamp(60px,7.2vw,116px); line-height:.84; letter-spacing:-.075em; margin:31px 0 30px; font-weight:770; }
|
||||
h1 em { font-family:Georgia,serif; font-weight:400; color:var(--orange); }
|
||||
.lede { font-size:18px; line-height:1.55; max-width:620px; color:#484a44; }
|
||||
.hero-actions { margin-top:38px; display:flex; align-items:center; gap:24px; }
|
||||
.primary-button { display:inline-flex; gap:24px; align-items:center; background:var(--ink); color:white; padding:18px 21px; font-weight:650; font-size:14px; }
|
||||
.primary-button span { color:var(--lime); font-size:20px; }
|
||||
.artifact-note { font:600 10px var(--font-geist-mono); color:var(--muted); text-transform:uppercase; letter-spacing:.08em; }
|
||||
.hero-metric { position:relative; border:1px solid var(--ink); padding:24px 25px 0; background:#e9e6dc; box-shadow:13px 13px 0 var(--ink); transform:rotate(1deg); }
|
||||
.metric-topline { display:flex; justify-content:space-between; font:600 10px var(--font-geist-mono); text-transform:uppercase; letter-spacing:.08em; }
|
||||
.verified { color:#497400; }
|
||||
.big-number { font-size:clamp(95px,12vw,184px); font-weight:800; line-height:.9; letter-spacing:-.085em; margin:25px 0 0; }
|
||||
.big-number span { color:var(--orange); font-size:.45em; vertical-align:top; position:relative; top:18px; }
|
||||
.metric-label { font-size:22px; font-weight:680; letter-spacing:-.03em; margin-bottom:35px; }
|
||||
.work-bars { display:grid; gap:12px; padding:20px 0; border-top:1px solid var(--line); }
|
||||
.work-row { display:grid; grid-template-columns:52px 1fr 52px; gap:12px; align-items:center; font:600 10px var(--font-geist-mono); }
|
||||
.work-row b { text-align:right; }
|
||||
.bar { height:11px; background:var(--ink); display:block; }
|
||||
.bar.after { width:9%; background:var(--orange); min-width:9px; }
|
||||
.hero-metric>p { font:500 10px/1.5 var(--font-geist-mono); color:var(--muted); }
|
||||
.honesty-strip { margin:20px -25px 0; padding:12px 25px; background:var(--lime); font:700 9px var(--font-geist-mono); text-transform:uppercase; letter-spacing:.07em; }
|
||||
.manifesto-band { background:var(--ink); color:white; min-height:74px; display:flex; align-items:center; justify-content:space-around; gap:24px; padding:16px 4vw; font:650 10px var(--font-geist-mono); text-transform:uppercase; letter-spacing:.08em; }
|
||||
.manifesto-band span::first-letter { color:var(--lime); }
|
||||
.section { padding:110px 6vw; }
|
||||
.section-heading { display:grid; grid-template-columns:1fr minmax(280px,440px); align-items:end; gap:40px; margin-bottom:58px; }
|
||||
h2 { font-size:clamp(43px,5vw,75px); line-height:.97; letter-spacing:-.058em; margin:18px 0 0; }
|
||||
.section-heading>p { color:var(--muted); line-height:1.6; font-size:14px; margin:0; }
|
||||
.run-context { display:grid; grid-template-columns:repeat(5,minmax(0,1fr)); border:1px solid var(--ink); border-bottom:0; background:#e8e5db; }
|
||||
.run-context span { min-width:0; padding:12px 14px; border-right:1px solid var(--line); font:500 9px/1.45 var(--font-geist-mono); color:var(--muted); text-transform:uppercase; }
|
||||
.run-context span:last-child { border-right:0; }
|
||||
.run-context b { color:var(--ink); margin-right:7px; }
|
||||
.comparison-table-wrap { overflow-x:auto; border:1px solid var(--ink); }
|
||||
.comparison-table { width:100%; min-width:1420px; border-collapse:collapse; table-layout:fixed; font-size:11px; }
|
||||
.comparison-table th,.comparison-table td { padding:14px 12px; text-align:left; border-right:1px solid var(--line); border-bottom:1px solid var(--line); vertical-align:middle; }
|
||||
.comparison-table th:last-child,.comparison-table td:last-child { border-right:0; }
|
||||
.comparison-table tbody tr:last-child>* { border-bottom:0; }
|
||||
.comparison-table thead { background:var(--ink); color:white; }
|
||||
.comparison-table thead th { padding-top:11px; padding-bottom:11px; font:650 9px/1.25 var(--font-geist-mono); text-transform:uppercase; letter-spacing:.06em; color:#deddd7; border-color:#3c3d38; }
|
||||
.comparison-table thead span { color:#858780; font-size:8px; }
|
||||
.comparison-table th:nth-child(1) { width:42px; }
|
||||
.comparison-table th:nth-child(2) { width:180px; }
|
||||
.comparison-table th:nth-child(3) { width:160px; }
|
||||
.comparison-table th:nth-child(4) { width:105px; }
|
||||
.comparison-table th:nth-child(5),.comparison-table th:nth-child(6) { width:92px; }
|
||||
.comparison-table th:nth-child(7),.comparison-table th:nth-child(8) { width:72px; }
|
||||
.comparison-table th:nth-child(9) { width:150px; }
|
||||
.comparison-table th:nth-child(10),.comparison-table th:nth-child(11) { width:100px; }
|
||||
.comparison-table th:nth-child(12) { width:82px; }
|
||||
.comparison-table tbody tr:hover { background:#eae7de; }
|
||||
.comparison-table tbody tr.measured { background:rgba(200,255,54,.11); }
|
||||
.comparison-table tbody tr.measured:hover { background:rgba(200,255,54,.2); }
|
||||
.comparison-table tbody tr.regression { background:rgba(255,180,53,.09); }
|
||||
.comparison-table tbody tr.rejected { background:rgba(255,107,53,.1); }
|
||||
.row-id { color:var(--muted); font:600 10px var(--font-geist-mono); }
|
||||
.variant-cell strong { display:block; font-size:12px; letter-spacing:-.015em; }
|
||||
.variant-cell span { display:block; margin-top:4px; color:var(--muted); font:500 8px var(--font-geist-mono); text-transform:uppercase; }
|
||||
.input-cell strong { display:block; font:650 10px var(--font-geist-mono); }
|
||||
.input-cell span { display:block; margin-top:4px; color:var(--muted); font:500 8px var(--font-geist-mono); }
|
||||
.metric-cell { font:650 11px var(--font-geist-mono); font-variant-numeric:tabular-nums; }
|
||||
.metric-cell strong { display:block; font:inherit; }
|
||||
.metric-cell span { display:block; margin-top:3px; color:var(--muted); font-size:8px; }
|
||||
.muted-cell { color:var(--muted); }
|
||||
.quality-ok { color:#557900; font-weight:700; }
|
||||
.speedup-cell { color:#456700; font:700 9px/1.45 var(--font-geist-mono); }
|
||||
.regression-cell { color:#a5421a; font:700 9px/1.45 var(--font-geist-mono); }
|
||||
.fidelity-cell { font-weight:750; color:#456700; }
|
||||
.quality-fail { color:#bd351f; font-weight:750; }
|
||||
.status { height:23px; padding:5px 9px; border:1px solid; border-radius:99px; font:700 8px var(--font-geist-mono); letter-spacing:.08em; text-transform:uppercase; }
|
||||
.status-measured { background:var(--lime); border-color:var(--lime); }
|
||||
.status-regression { color:#8a4710; background:#ffe0a3; border-color:#f2bd58; }
|
||||
.status-rejected { color:#9e2d1c; background:#ffd3c4; border-color:#ff9e7b; }
|
||||
.status-ready,.status-queued { color:#ad451c; background:#ffe1d5; border-color:#ffc1a9; }
|
||||
.status-planned { color:var(--muted); border-color:var(--line); }
|
||||
.table-notes { display:flex; gap:26px; padding:13px 2px 0; color:var(--muted); font:500 9px var(--font-geist-mono); }
|
||||
.table-notes b { color:var(--ink); margin-right:5px; }
|
||||
.quality-section { background:var(--ink); color:white; padding:115px 6vw; display:grid; grid-template-columns:.8fr 1.2fr; gap:8vw; }
|
||||
.quality-intro>p { color:#aaa9a3; max-width:480px; line-height:1.6; margin-top:24px; }
|
||||
.gate-formula { display:flex; flex-direction:column; gap:9px; margin-top:45px; border-left:2px solid var(--lime); padding:4px 0 4px 18px; }
|
||||
.gate-formula span { color:#8c8d87; font:600 9px var(--font-geist-mono); text-transform:uppercase; }
|
||||
.gate-formula code { color:var(--lime); font-size:13px; }
|
||||
.quality-table { border-top:1px solid #555650; }
|
||||
.quality-row { display:grid; grid-template-columns:1fr 1.25fr 1fr; gap:15px; padding:23px 10px; border-bottom:1px solid #3b3c37; font-size:12px; }
|
||||
.quality-row.header { color:#777973; font:600 9px var(--font-geist-mono); text-transform:uppercase; }
|
||||
.quality-row span { color:#aaa9a3; }
|
||||
.quality-row b { color:var(--lime); font:600 10px var(--font-geist-mono); }
|
||||
.quality-proof { background:var(--lime); color:var(--ink); margin-top:24px; padding:22px; display:flex; gap:17px; }
|
||||
.proof-icon { display:grid; place-items:center; flex:0 0 36px; height:36px; border-radius:99px; background:var(--ink); color:var(--lime); }
|
||||
.quality-proof strong { font-size:14px; }
|
||||
.quality-proof p { margin:5px 0 0; font-size:11px; line-height:1.5; }
|
||||
.protocol-heading { align-items:center; }
|
||||
.commit-chip { justify-self:end; border:1px solid var(--line); padding:11px 15px; font:500 10px var(--font-geist-mono); }
|
||||
.commit-chip code { color:var(--orange); }
|
||||
.protocol-grid { display:grid; grid-template-columns:repeat(4,1fr); border-top:1px solid var(--ink); border-bottom:1px solid var(--ink); }
|
||||
.protocol-grid article { min-height:230px; padding:25px; border-right:1px solid var(--line); }
|
||||
.protocol-grid article:last-child { border-right:0; }
|
||||
.protocol-grid article>span { color:var(--orange); font:700 11px var(--font-geist-mono); }
|
||||
.protocol-grid h3 { margin:48px 0 10px; font-size:23px; letter-spacing:-.04em; }
|
||||
.protocol-grid p { color:var(--muted); font-size:12px; line-height:1.6; }
|
||||
.metric-strip { margin-top:60px; display:grid; grid-template-columns:repeat(5,1fr); background:#e7e4da; }
|
||||
.metric-strip>div { padding:21px; border-right:1px solid var(--paper); }
|
||||
.metric-strip small { display:block; color:var(--muted); font:600 9px var(--font-geist-mono); text-transform:uppercase; margin-bottom:8px; }
|
||||
.metric-strip strong { font-size:13px; }
|
||||
.next-run { background:var(--orange); padding:80px 6vw; display:grid; grid-template-columns:1.2fr .8fr; gap:8vw; align-items:end; }
|
||||
.next-run .eyebrow { color:var(--ink); }
|
||||
.next-run-copy { line-height:1.6; font-size:14px; }
|
||||
.next-run-copy a { font:700 10px var(--font-geist-mono); text-transform:uppercase; border-bottom:1px solid; padding-bottom:4px; }
|
||||
footer { min-height:110px; padding:25px 4.5vw; background:var(--ink); color:#aaa9a3; display:flex; justify-content:space-between; align-items:center; font-size:10px; }
|
||||
footer .brand { color:white; }
|
||||
|
||||
@media (max-width:900px) {
|
||||
nav { display:none; }
|
||||
.hero { grid-template-columns:1fr; padding-top:60px; }
|
||||
.hero-metric { max-width:600px; }
|
||||
.section-heading,.quality-section,.next-run { grid-template-columns:1fr; }
|
||||
.protocol-grid { grid-template-columns:1fr 1fr; }
|
||||
.protocol-grid article:nth-child(2) { border-right:0; }
|
||||
.metric-strip { grid-template-columns:1fr 1fr; }
|
||||
.run-context { grid-template-columns:1fr 1fr; }
|
||||
.run-context span:nth-child(2) { border-right:0; }
|
||||
.run-context span:nth-child(-n+2) { border-bottom:1px solid var(--line); }
|
||||
}
|
||||
@media (max-width:560px) {
|
||||
.topbar { padding:0 20px; }
|
||||
.repo-link { font-size:9px; }
|
||||
.hero,.section,.quality-section,.next-run { padding-left:22px; padding-right:22px; }
|
||||
h1 { font-size:58px; }
|
||||
.hero-actions { align-items:flex-start; flex-direction:column; }
|
||||
.manifesto-band { justify-content:flex-start; overflow:auto; }
|
||||
.manifesto-band span { white-space:nowrap; }
|
||||
.section-heading { grid-template-columns:1fr; }
|
||||
.run-context { grid-template-columns:1fr; }
|
||||
.run-context span { border-right:0; border-bottom:1px solid var(--line); }
|
||||
.run-context span:nth-child(3) { border-bottom:1px solid var(--line); }
|
||||
.table-notes { flex-direction:column; gap:7px; }
|
||||
.quality-row { grid-template-columns:.75fr 1.2fr; }
|
||||
.quality-row>*:last-child { grid-column:2; }
|
||||
.protocol-grid,.metric-strip { grid-template-columns:1fr; }
|
||||
.protocol-grid article { border-right:0; border-bottom:1px solid var(--line); }
|
||||
footer { align-items:flex-start; gap:20px; flex-direction:column; }
|
||||
}
|
||||
@media (prefers-reduced-motion:reduce) { html { scroll-behavior:auto; } * { transition:none!important; } }
|
||||
@@ -0,0 +1,37 @@
|
||||
import type { Metadata } from "next";
|
||||
import { Geist, Geist_Mono } from "next/font/google";
|
||||
import { headers } from "next/headers";
|
||||
import "./globals.css";
|
||||
|
||||
const geistSans = Geist({ variable: "--font-geist-sans", subsets: ["latin"] });
|
||||
const geistMono = Geist_Mono({ variable: "--font-geist-mono", subsets: ["latin"] });
|
||||
|
||||
export async function generateMetadata(): Promise<Metadata> {
|
||||
const requestHeaders = await headers();
|
||||
const host = requestHeaders.get("x-forwarded-host") ?? requestHeaders.get("host") ?? "localhost:3000";
|
||||
const protocol = requestHeaders.get("x-forwarded-proto") ?? (host.startsWith("localhost") ? "http" : "https");
|
||||
const origin = `${protocol}://${host}`;
|
||||
return {
|
||||
metadataBase: new URL(origin),
|
||||
title: { default: "VLM Speed Lab", template: "%s · VLM Speed Lab" },
|
||||
description: "Measured VLM speedups with reproducible quality evidence.",
|
||||
icons: { icon: "/favicon.svg", shortcut: "/favicon.svg" },
|
||||
openGraph: {
|
||||
title: "VLM Speed Lab",
|
||||
description: "Make it faster. Prove it stayed good.",
|
||||
type: "website",
|
||||
url: origin,
|
||||
images: [{ url: `${origin}/og.png`, width: 1200, height: 630, alt: "VLM Speed Lab — measured, not marketed" }],
|
||||
},
|
||||
twitter: {
|
||||
card: "summary_large_image",
|
||||
title: "VLM Speed Lab",
|
||||
description: "Make it faster. Prove it stayed good.",
|
||||
images: [`${origin}/og.png`],
|
||||
},
|
||||
};
|
||||
}
|
||||
|
||||
export default function RootLayout({ children }: Readonly<{ children: React.ReactNode }>) {
|
||||
return <html lang="en"><body className={`${geistSans.variable} ${geistMono.variable}`}>{children}</body></html>;
|
||||
}
|
||||
@@ -0,0 +1,407 @@
|
||||
import type { Metadata } from "next";
|
||||
|
||||
export const metadata: Metadata = {
|
||||
title: "VLM Speed Lab — Qwen3-VL 2B",
|
||||
description:
|
||||
"Reproducible VLM performance iterations with latency, throughput, memory, and quality evidence.",
|
||||
};
|
||||
|
||||
const iterations = [
|
||||
{
|
||||
id: "00",
|
||||
name: "Source-resolution control",
|
||||
stack: "BF16 · SDPA · dynamic",
|
||||
input: "2048×1365",
|
||||
tokens: "11,008 vision · 2,770 input",
|
||||
status: "measured",
|
||||
change: "Frozen control",
|
||||
ttft: ["700.3", "723.1"],
|
||||
e2e: ["1395.7", "1487.7"],
|
||||
throughput: "42.3",
|
||||
vram: "4.55",
|
||||
speedup: "1.00× / 1.00× / 1.00×",
|
||||
quality: "4/4 concepts",
|
||||
exact: "10/10",
|
||||
},
|
||||
{
|
||||
id: "01a",
|
||||
name: "Medium visual budget",
|
||||
stack: "BF16 · SDPA · dynamic",
|
||||
input: "672×448",
|
||||
tokens: "1,176 vision · 312 input",
|
||||
status: "measured",
|
||||
change: "Resize only",
|
||||
ttft: ["112.8", "122.8"],
|
||||
e2e: ["844.0", "881.7"],
|
||||
throughput: "42.2",
|
||||
vram: "4.04",
|
||||
speedup: "6.21× / 1.65× / 1.00×",
|
||||
quality: "4/4 concepts",
|
||||
exact: "Semantic",
|
||||
},
|
||||
{
|
||||
id: "01b",
|
||||
name: "Aggressive visual budget",
|
||||
stack: "BF16 · SDPA · dynamic",
|
||||
input: "448×299",
|
||||
tokens: "504 vision · 144 input",
|
||||
status: "measured",
|
||||
change: "Resize only",
|
||||
ttft: ["88.2", "90.2"],
|
||||
e2e: ["774.1", "780.5"],
|
||||
throughput: "43.7",
|
||||
vram: "4.00",
|
||||
speedup: "7.94× / 1.80× / 1.03×",
|
||||
quality: "4/4 concepts",
|
||||
exact: "Semantic",
|
||||
},
|
||||
{
|
||||
id: "02",
|
||||
name: "Compiled execution",
|
||||
stack: "BF16 · SDPA · static cache",
|
||||
input: "448×299",
|
||||
tokens: "504 vision · 144 input",
|
||||
status: "measured",
|
||||
change: "Cache + compile",
|
||||
ttft: ["76.6", "77.3"],
|
||||
e2e: ["290.1", "299.7"],
|
||||
throughput: "139.4",
|
||||
vram: "4.02",
|
||||
speedup: "9.14× / 4.81× / 3.30×",
|
||||
quality: "4/4 concepts",
|
||||
exact: "Exact vs 01b",
|
||||
},
|
||||
{
|
||||
id: "03a",
|
||||
name: "Flash Attention 2 isolated",
|
||||
stack: "BF16 · FA2 · dynamic",
|
||||
input: "448×299",
|
||||
tokens: "504 vision · 144 input",
|
||||
status: "regression",
|
||||
change: "Attention kernel",
|
||||
ttft: ["106.6", "114.0"],
|
||||
e2e: ["1033.3", "1054.4"],
|
||||
throughput: "32.3",
|
||||
vram: "4.00",
|
||||
speedup: "6.57× / 1.35× / 0.76×",
|
||||
quality: "PASS",
|
||||
exact: "Exact vs 01b",
|
||||
},
|
||||
{
|
||||
id: "03b",
|
||||
name: "FA2 + compiled decode",
|
||||
stack: "BF16 · FA2 · static cache",
|
||||
input: "448×299",
|
||||
tokens: "hit 96-token cap",
|
||||
status: "rejected",
|
||||
change: "Cache + compile",
|
||||
ttft: ["265.0", "273.8"],
|
||||
e2e: ["3028.0", "3042.9"],
|
||||
throughput: "34.4",
|
||||
vram: "4.02",
|
||||
speedup: "2.64× / 0.46× / 0.81×",
|
||||
quality: "FAIL",
|
||||
exact: "Corrupt repeat",
|
||||
},
|
||||
{
|
||||
id: "04",
|
||||
name: "Scoped TF32",
|
||||
stack: "BF16 · SDPA · static · TF32",
|
||||
input: "448×299",
|
||||
tokens: "504 vision · 144 input",
|
||||
status: "measured",
|
||||
change: "FP32 matmul policy",
|
||||
ttft: ["74.3", "79.5"],
|
||||
e2e: ["274.5", "289.6"],
|
||||
throughput: "149.2",
|
||||
vram: "4.03",
|
||||
speedup: "9.43× / 5.08× / 3.53×",
|
||||
quality: "4/4 concepts",
|
||||
exact: "Exact vs 01b",
|
||||
},
|
||||
{
|
||||
id: "05a",
|
||||
name: "SGLang 0.5.9 native",
|
||||
stack: "FlashInfer · SDPA vision",
|
||||
input: "448×299",
|
||||
tokens: "2 output tokens",
|
||||
status: "rejected",
|
||||
change: "Serving runtime",
|
||||
ttft: ["38.3", "42.9"],
|
||||
e2e: ["43.3", "48.0"],
|
||||
throughput: "393.9",
|
||||
vram: null,
|
||||
speedup: "Invalid — gate failed",
|
||||
quality: "0/4 concepts",
|
||||
exact: "Output was ```",
|
||||
},
|
||||
{
|
||||
id: "05b",
|
||||
name: "SGLang 0.5.10 TF backend",
|
||||
stack: "FlashInfer · Transformers VLM",
|
||||
input: "448×299",
|
||||
tokens: "144 input · 31 output",
|
||||
status: "measured",
|
||||
change: "Version + model impl",
|
||||
ttft: ["75.6", "79.2"],
|
||||
e2e: ["254.2", "257.5"],
|
||||
throughput: "173.5",
|
||||
vram: null,
|
||||
speedup: "9.26× / 5.49× / 4.10×",
|
||||
quality: "4/4 concepts",
|
||||
exact: "Exact vs 01b",
|
||||
},
|
||||
{
|
||||
id: "05c",
|
||||
name: "SGLang 0.5.10 native",
|
||||
stack: "FlashInfer · SDPA vision",
|
||||
input: "448×299",
|
||||
tokens: "144 input · 40 output",
|
||||
status: "measured",
|
||||
change: "Native model impl",
|
||||
ttft: ["35.2", "38.3"],
|
||||
e2e: ["240.6", "243.6"],
|
||||
throughput: "194.7",
|
||||
vram: null,
|
||||
speedup: "19.88× / 5.80× / 4.60×",
|
||||
quality: "4/4 concepts",
|
||||
exact: "Semantic",
|
||||
},
|
||||
{
|
||||
id: "05d",
|
||||
name: "Triton vision attention",
|
||||
stack: "FlashInfer · Triton vision",
|
||||
input: "448×299",
|
||||
tokens: "144 input · 31 output",
|
||||
status: "measured",
|
||||
change: "Vision attention only",
|
||||
ttft: ["35.5", "37.9"],
|
||||
e2e: ["193.6", "195.3"],
|
||||
throughput: "196.4",
|
||||
vram: null,
|
||||
speedup: "19.74× / 7.21× / 4.64×",
|
||||
quality: "4/4 concepts",
|
||||
exact: "Exact vs 01b",
|
||||
},
|
||||
{
|
||||
id: "05e",
|
||||
name: "Compiled SGLang decode",
|
||||
stack: "FlashInfer · Triton · compile",
|
||||
input: "448×299",
|
||||
tokens: "144 input · 31 output",
|
||||
status: "measured",
|
||||
change: "Torch compile only",
|
||||
ttft: ["37.5", "41.0"],
|
||||
e2e: ["190.5", "194.7"],
|
||||
throughput: "202.6",
|
||||
vram: null,
|
||||
speedup: "18.69× / 7.33× / 4.79×",
|
||||
quality: "4/4 concepts",
|
||||
exact: "Exact vs 01b",
|
||||
},
|
||||
{
|
||||
id: "06",
|
||||
name: "TensorRT vision engine",
|
||||
stack: "TRT 10.13 · BF16 · static",
|
||||
input: "448×299",
|
||||
tokens: "504 vision · 144 input · 31 output",
|
||||
status: "measured",
|
||||
change: "Vision tower only",
|
||||
ttft: ["61.4", "62.4"],
|
||||
e2e: ["273.4", "274.0"],
|
||||
throughput: "142.1",
|
||||
vram: "4.02",
|
||||
speedup: "11.41× / 5.10× / 3.36×",
|
||||
quality: "4/4 concepts",
|
||||
exact: "Exact vs Torch 2.9",
|
||||
},
|
||||
{
|
||||
id: "07",
|
||||
name: "TensorRT + SGLang bridge",
|
||||
stack: "TRT vision · SGLang decode",
|
||||
input: "448×299",
|
||||
tokens: "144 input · 40 output",
|
||||
status: "regression",
|
||||
change: "Runtime composition",
|
||||
ttft: ["34.9", "37.8"],
|
||||
e2e: ["250.7", "366.1"],
|
||||
throughput: "176.1",
|
||||
vram: null,
|
||||
speedup: "20.09× / 5.57× / 4.16×",
|
||||
quality: "4/4 concepts",
|
||||
exact: "Semantic · exact fail",
|
||||
},
|
||||
];
|
||||
|
||||
const qualityTasks = [
|
||||
["Caption facts", "concept groups + aliases", "4 / 4 in every run"],
|
||||
["Resize fidelity", "task rubric", "pass · wording changed"],
|
||||
["Compiler fidelity", "SHA-256 output", "exact vs iteration 01b"],
|
||||
["Repeatability", "within variant", "10 / 10 identical"],
|
||||
];
|
||||
|
||||
export default function Home() {
|
||||
return (
|
||||
<main>
|
||||
<header className="topbar">
|
||||
<a className="brand" href="#top" aria-label="VLM Speed Lab home">
|
||||
<span className="brand-mark">VL</span>
|
||||
<span>VLM Speed Lab</span>
|
||||
</a>
|
||||
<nav aria-label="Primary navigation">
|
||||
<a href="#iterations">Iterations</a>
|
||||
<a href="#quality">Quality gate</a>
|
||||
<a href="#protocol">Protocol</a>
|
||||
</nav>
|
||||
<a className="repo-link" href="https://github.com/gokayfem/ComfyUI_VLM_nodes">
|
||||
View repository ↗
|
||||
</a>
|
||||
</header>
|
||||
|
||||
<section className="hero" id="top">
|
||||
<div className="hero-copy">
|
||||
<div className="eyebrow"><span className="live-dot" /> Experiment 001 · Qwen3-VL 2B Instruct</div>
|
||||
<h1>Make it faster.<br /><em>Prove</em> it stayed good.</h1>
|
||||
<p className="lede">
|
||||
One model. One frozen test set. One change per iteration. Every speed claim ships with its output, configuration, and quality score.
|
||||
</p>
|
||||
<div className="hero-actions">
|
||||
<a className="primary-button" href="#iterations">Explore the iterations <span>↓</span></a>
|
||||
<span className="artifact-note">No synthetic leaderboard numbers</span>
|
||||
</div>
|
||||
</div>
|
||||
|
||||
<div className="hero-metric" aria-label="Measured end-to-end speedup">
|
||||
<div className="metric-topline"><span>Measured now</span><span className="verified">● VERIFIED</span></div>
|
||||
<div className="big-number">7.33<span>×</span></div>
|
||||
<div className="metric-label">faster end to end</div>
|
||||
<div className="work-bars" aria-hidden="true">
|
||||
<div className="work-row"><span>Before</span><i className="bar before" /><b>1395.7</b></div>
|
||||
<div className="work-row"><span>After</span><i className="bar after" /><b>190.5</b></div>
|
||||
</div>
|
||||
<p>Milliseconds p50 · 10 measured runs · output throughput 42.3 → 202.6 tok/s</p>
|
||||
<div className="honesty-strip">RTX 3090 · batch 1 · task rubric passed · raw samples attached</div>
|
||||
</div>
|
||||
</section>
|
||||
|
||||
<section className="manifesto-band" aria-label="Benchmark principles">
|
||||
<span>01 / Same checkpoint</span>
|
||||
<span>02 / Same media</span>
|
||||
<span>03 / Same decode</span>
|
||||
<span>04 / Quality gated</span>
|
||||
<span>05 / Raw artifacts</span>
|
||||
</section>
|
||||
|
||||
<section className="section iterations-section" id="iterations">
|
||||
<div className="section-heading">
|
||||
<div>
|
||||
<div className="eyebrow">THE OPTIMIZATION LOG</div>
|
||||
<h2>Every millisecond has a paper trail.</h2>
|
||||
</div>
|
||||
<p>Primary numbers are p50; the smaller number is p95. Every row keeps input work, memory, speedup, and quality evidence in view.</p>
|
||||
</div>
|
||||
|
||||
<div className="run-context" aria-label="Benchmark run context">
|
||||
<span><b>Model</b> Qwen3-VL 2B Instruct</span>
|
||||
<span><b>Mode</b> Single request</span>
|
||||
<span><b>Sample</b> 10 measured / variant</span>
|
||||
<span><b>Warmup</b> 2–6 local / 3 server</span>
|
||||
<span><b>Runtime</b> Torch 2.8/2.9 · SGLang 0.5.10 · TRT 10.13</span>
|
||||
</div>
|
||||
|
||||
<div className="comparison-table-wrap">
|
||||
<table className="comparison-table">
|
||||
<thead>
|
||||
<tr>
|
||||
<th scope="col">#</th>
|
||||
<th scope="col">Variant</th>
|
||||
<th scope="col">Input work</th>
|
||||
<th scope="col">One change</th>
|
||||
<th scope="col">TTFT<br /><span>p50 / p95 ms</span></th>
|
||||
<th scope="col">E2E<br /><span>p50 / p95 ms</span></th>
|
||||
<th scope="col">Output<br /><span>tok/s</span></th>
|
||||
<th scope="col">Peak<br /><span>VRAM GiB</span></th>
|
||||
<th scope="col">Speedup<br /><span>TTFT / E2E / tok/s</span></th>
|
||||
<th scope="col">Quality</th>
|
||||
<th scope="col">Output fidelity</th>
|
||||
<th scope="col">Status</th>
|
||||
</tr>
|
||||
</thead>
|
||||
<tbody>
|
||||
{iterations.map((item) => (
|
||||
<tr className={item.status} key={item.id}>
|
||||
<td className="row-id">{item.id}</td>
|
||||
<th scope="row" className="variant-cell"><strong>{item.name}</strong><span>{item.stack}</span></th>
|
||||
<td className="input-cell"><strong>{item.input}</strong><span>{item.tokens}</span></td>
|
||||
<td>{item.change}</td>
|
||||
<td className="metric-cell">{item.ttft ? <><strong>{item.ttft[0]}</strong><span>{item.ttft[1]}</span></> : "—"}</td>
|
||||
<td className="metric-cell">{item.e2e ? <><strong>{item.e2e[0]}</strong><span>{item.e2e[1]}</span></> : "—"}</td>
|
||||
<td className="metric-cell">{item.throughput ?? "—"}</td>
|
||||
<td className="metric-cell">{item.vram ?? "—"}</td>
|
||||
<td className={item.status === "measured" ? "speedup-cell" : item.status === "planned" ? "muted-cell" : "regression-cell"}>{item.speedup}</td>
|
||||
<td className={item.status === "rejected" ? "quality-fail" : item.status === "planned" ? "muted-cell" : "quality-ok"}>{item.quality}</td>
|
||||
<td className={item.status === "rejected" ? "quality-fail" : item.status === "planned" ? "muted-cell" : "fidelity-cell"}>{item.exact}</td>
|
||||
<td><span className={`status status-${item.status}`}>{item.status}</span></td>
|
||||
</tr>
|
||||
))}
|
||||
</tbody>
|
||||
</table>
|
||||
</div>
|
||||
<div className="table-notes">
|
||||
<span><b>—</b> Not measured; never estimated</span>
|
||||
<span><b>Semantic</b> Required facts pass; wording changed</span>
|
||||
<span><b>Exact</b> SHA-256-identical generated text</span>
|
||||
<span><b>VRAM —</b> Server peak not yet instrumented</span>
|
||||
<span><b>Load</b> 88.351s → 6.858s warm cache</span>
|
||||
<span><b>TRT</b> 1 engine · 0 fallback · 98.070s compile</span>
|
||||
</div>
|
||||
</section>
|
||||
|
||||
<section className="quality-section" id="quality">
|
||||
<div className="quality-intro">
|
||||
<div className="eyebrow light">QUALITY IS A HARD CONSTRAINT</div>
|
||||
<h2>Fast and wrong<br />doesn’t ship.</h2>
|
||||
<p>A speedup is promoted only after it clears its declared task gate. Semantic preservation and exact bytes are reported separately.</p>
|
||||
<div className="gate-formula"><span>promotion rule</span><code>speed ↑ && quality ≥ tolerance</code></div>
|
||||
</div>
|
||||
<div className="quality-table" role="table" aria-label="Quality thresholds">
|
||||
<div className="quality-row header" role="row"><span>Capability</span><span>Primary score</span><span>Pass threshold</span></div>
|
||||
{qualityTasks.map(([task, metric, threshold]) => (
|
||||
<div className="quality-row" role="row" key={task}><strong>{task}</strong><span>{metric}</span><b>{threshold}</b></div>
|
||||
))}
|
||||
<div className="quality-proof">
|
||||
<span className="proof-icon">✓</span>
|
||||
<div><strong>Outputs stay attached</strong><p>Prompts, model text, boxes, masks, tracks, timing traces, and environment metadata live beside each result.</p></div>
|
||||
</div>
|
||||
</div>
|
||||
</section>
|
||||
|
||||
<section className="section protocol-section" id="protocol">
|
||||
<div className="section-heading protocol-heading">
|
||||
<div><div className="eyebrow">REPRODUCIBLE BY DEFAULT</div><h2>The benchmark contract.</h2></div>
|
||||
<div className="commit-chip">artifact <code>TF5 · RTX3090 · B1</code></div>
|
||||
</div>
|
||||
<div className="protocol-grid">
|
||||
<article><span>1</span><h3>Freeze</h3><p>Checkpoint revision, media hashes, prompts, seed, precision, and generation parameters.</p></article>
|
||||
<article><span>2</span><h3>Warm</h3><p>Cold start is recorded once. Warmups are declared and excluded from steady-state percentiles.</p></article>
|
||||
<article><span>3</span><h3>Measure</h3><p>TTFT, inter-token latency, output tokens/sec, end-to-end time, peak VRAM, and concurrency.</p></article>
|
||||
<article><span>4</span><h3>Gate</h3><p>Compare outputs to the baseline and ground truth. Publish pass, regression, or inconclusive.</p></article>
|
||||
</div>
|
||||
<div className="metric-strip">
|
||||
<div><small>Latency</small><strong>p50 / p95 / p99</strong></div>
|
||||
<div><small>Throughput</small><strong>output tok/s</strong></div>
|
||||
<div><small>Responsiveness</small><strong>TTFT + ITL</strong></div>
|
||||
<div><small>Efficiency</small><strong>GB VRAM / request</strong></div>
|
||||
<div><small>Quality</small><strong>task-specific score</strong></div>
|
||||
</div>
|
||||
</section>
|
||||
|
||||
<section className="next-run">
|
||||
<div><span className="eyebrow light">NEXT ON THE RIG</span><h2>Recover exact output.</h2></div>
|
||||
<div className="next-run-copy"><p>The bridge cut TTFT to 34.9 ms, but changed the exact caption and generated 40 tokens, raising end-to-end latency to 250.7 ms. Next: compile SGLang-native vision weights so TensorRT preserves the 31-token output.</p><a href="https://github.com/gokayfem/ComfyUI_VLM_nodes/tree/codex/vlm-benchmark-lab/benchmarks">Open benchmark kit ↗</a></div>
|
||||
</section>
|
||||
|
||||
<footer><div className="brand"><span className="brand-mark">VL</span><span>VLM Speed Lab</span></div><p>Built in public. Measured, not marketed.</p><span>ComfyUI VLM Nodes · 2026</span></footer>
|
||||
</main>
|
||||
);
|
||||
}
|
||||
@@ -0,0 +1,45 @@
|
||||
import { access, cp, mkdir, rm } from "node:fs/promises";
|
||||
import { resolve } from "node:path";
|
||||
import type { Plugin } from "vite";
|
||||
|
||||
async function exists(path: string): Promise<boolean> {
|
||||
try {
|
||||
await access(path);
|
||||
return true;
|
||||
} catch (error) {
|
||||
if ((error as NodeJS.ErrnoException).code === "ENOENT") {
|
||||
return false;
|
||||
}
|
||||
throw error;
|
||||
}
|
||||
}
|
||||
|
||||
// Packages Sites metadata and migrations after Vite finishes compiling.
|
||||
export function sites(): Plugin {
|
||||
let root = process.cwd();
|
||||
|
||||
return {
|
||||
name: "sites",
|
||||
apply: "build",
|
||||
configResolved(config) {
|
||||
root = config.root;
|
||||
},
|
||||
async closeBundle() {
|
||||
const outputDirectory = resolve(root, "dist", ".openai");
|
||||
const hostingConfig = resolve(root, ".openai", "hosting.json");
|
||||
const drizzleSource = resolve(root, "drizzle");
|
||||
|
||||
await rm(outputDirectory, { recursive: true, force: true });
|
||||
await mkdir(outputDirectory, { recursive: true });
|
||||
|
||||
if (await exists(hostingConfig)) {
|
||||
await cp(hostingConfig, resolve(outputDirectory, "hosting.json"));
|
||||
}
|
||||
if (await exists(drizzleSource)) {
|
||||
await cp(drizzleSource, resolve(outputDirectory, "drizzle"), {
|
||||
recursive: true,
|
||||
});
|
||||
}
|
||||
},
|
||||
};
|
||||
}
|
||||
@@ -0,0 +1,13 @@
|
||||
import { env } from "cloudflare:workers";
|
||||
import { drizzle } from "drizzle-orm/d1";
|
||||
import * as schema from "./schema";
|
||||
|
||||
export function getDb() {
|
||||
if (!env.DB) {
|
||||
throw new Error(
|
||||
"Cloudflare D1 binding `DB` is unavailable. Set the `d1` field in .openai/hosting.json to `DB` or let your control plane inject the real binding values before using the database."
|
||||
);
|
||||
}
|
||||
|
||||
return drizzle(env.DB, { schema });
|
||||
}
|
||||
@@ -0,0 +1,4 @@
|
||||
// Intentionally empty by default.
|
||||
// Add Drizzle tables here when the site actually needs a database.
|
||||
// See examples/d1/db/schema.ts for an opt-in example.
|
||||
export {};
|
||||
@@ -0,0 +1,7 @@
|
||||
import { defineConfig } from "drizzle-kit";
|
||||
|
||||
export default defineConfig({
|
||||
out: "./drizzle",
|
||||
schema: "./db/schema.ts",
|
||||
dialect: "sqlite",
|
||||
});
|
||||
@@ -0,0 +1,5 @@
|
||||
{
|
||||
"version": "7",
|
||||
"dialect": "sqlite",
|
||||
"entries": []
|
||||
}
|
||||
@@ -0,0 +1,41 @@
|
||||
import { defineConfig, globalIgnores } from "eslint/config";
|
||||
import eslint from "@eslint/js";
|
||||
import next from "@next/eslint-plugin-next";
|
||||
import jsxA11y from "eslint-plugin-jsx-a11y";
|
||||
import react from "eslint-plugin-react";
|
||||
import reactHooks from "eslint-plugin-react-hooks";
|
||||
import globals from "globals";
|
||||
import tseslint from "typescript-eslint";
|
||||
|
||||
const eslintConfig = defineConfig([
|
||||
globalIgnores([
|
||||
".next/**",
|
||||
"dist/**",
|
||||
"out/**",
|
||||
"build/**",
|
||||
"next-env.d.ts",
|
||||
]),
|
||||
eslint.configs.recommended,
|
||||
...tseslint.configs.recommended,
|
||||
react.configs.flat.recommended,
|
||||
react.configs.flat["jsx-runtime"],
|
||||
reactHooks.configs.flat["recommended-latest"],
|
||||
jsxA11y.flatConfigs.recommended,
|
||||
next.configs["core-web-vitals"],
|
||||
{
|
||||
languageOptions: {
|
||||
globals: {
|
||||
...globals.browser,
|
||||
...globals.node,
|
||||
...globals.serviceworker,
|
||||
},
|
||||
},
|
||||
settings: {
|
||||
react: {
|
||||
version: "detect",
|
||||
},
|
||||
},
|
||||
},
|
||||
]);
|
||||
|
||||
export default eslintConfig;
|
||||
@@ -0,0 +1,58 @@
|
||||
import { desc } from "drizzle-orm";
|
||||
import { getDb } from "../../../../../db";
|
||||
import { notes } from "../../../db/schema";
|
||||
|
||||
function toRouteErrorMessage(error: unknown) {
|
||||
const message = error instanceof Error ? error.message : "Unexpected error";
|
||||
const detail =
|
||||
error instanceof Error && error.cause instanceof Error ? error.cause.message : "";
|
||||
const combined = `${message}\n${detail}`;
|
||||
|
||||
if (combined.includes("no such table") || combined.includes('from "notes"')) {
|
||||
return "The notes table is unavailable. Generate the migration locally with `npm run db:generate`, then deploy so the platform can apply the generated SQL to the real D1 database.";
|
||||
}
|
||||
|
||||
return message;
|
||||
}
|
||||
|
||||
export async function GET() {
|
||||
try {
|
||||
const db = getDb();
|
||||
const rows = await db
|
||||
.select()
|
||||
.from(notes)
|
||||
.orderBy(desc(notes.createdAt), desc(notes.id))
|
||||
.limit(20);
|
||||
|
||||
return Response.json({ notes: rows });
|
||||
} catch (error) {
|
||||
return Response.json(
|
||||
{ error: toRouteErrorMessage(error) },
|
||||
{ status: 500 }
|
||||
);
|
||||
}
|
||||
}
|
||||
|
||||
export async function POST(request: Request) {
|
||||
try {
|
||||
const payload = (await request.json()) as {
|
||||
title?: string;
|
||||
content?: string;
|
||||
};
|
||||
const title = payload.title?.trim() ?? "";
|
||||
const content = payload.content?.trim() ?? "";
|
||||
|
||||
if (!title) {
|
||||
return Response.json({ error: "title is required" }, { status: 400 });
|
||||
}
|
||||
|
||||
const db = getDb();
|
||||
const [note] = await db.insert(notes).values({ title, content }).returning();
|
||||
return Response.json({ note }, { status: 201 });
|
||||
} catch (error) {
|
||||
return Response.json(
|
||||
{ error: toRouteErrorMessage(error) },
|
||||
{ status: 500 }
|
||||
);
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,9 @@
|
||||
import { sql } from "drizzle-orm";
|
||||
import { integer, sqliteTable, text } from "drizzle-orm/sqlite-core";
|
||||
|
||||
export const notes = sqliteTable("notes", {
|
||||
id: integer("id").primaryKey({ autoIncrement: true }),
|
||||
title: text("title").notNull(),
|
||||
content: text("content").notNull().default(""),
|
||||
createdAt: text("created_at").notNull().default(sql`CURRENT_TIMESTAMP`),
|
||||
});
|
||||
Vendored
+5
@@ -0,0 +1,5 @@
|
||||
import "vinext/types";
|
||||
import "./.next/types/routes.d.ts";
|
||||
|
||||
// NOTE: This file should not be edited
|
||||
// see https://nextjs.org/docs/app/api-reference/config/typescript for more information.
|
||||
@@ -0,0 +1,7 @@
|
||||
import type { NextConfig } from "next";
|
||||
|
||||
const nextConfig: NextConfig = {
|
||||
/* config options here */
|
||||
};
|
||||
|
||||
export default nextConfig;
|
||||
Generated
+10269
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,46 @@
|
||||
{
|
||||
"name": "site-creator-vinext-starter",
|
||||
"version": "0.1.0",
|
||||
"private": true,
|
||||
"engines": {
|
||||
"node": ">=22.13.0"
|
||||
},
|
||||
"scripts": {
|
||||
"dev": "WRANGLER_LOG_PATH=.wrangler/wrangler.log vinext dev",
|
||||
"build": "WRANGLER_LOG_PATH=.wrangler/wrangler.log vinext build",
|
||||
"start": "WRANGLER_LOG_PATH=.wrangler/wrangler.log vinext start",
|
||||
"test": "npm run build && node --test tests/rendered-html.test.mjs",
|
||||
"lint": "eslint . --ignore-pattern dist --ignore-pattern .next",
|
||||
"db:generate": "drizzle-kit generate"
|
||||
},
|
||||
"dependencies": {
|
||||
"drizzle-orm": "0.45.2",
|
||||
"react": "19.2.6",
|
||||
"react-dom": "19.2.6"
|
||||
},
|
||||
"devDependencies": {
|
||||
"@cloudflare/vite-plugin": "1.37.1",
|
||||
"@eslint/js": "9.39.4",
|
||||
"@next/eslint-plugin-next": "16.2.6",
|
||||
"@tailwindcss/postcss": "4.2.1",
|
||||
"@types/node": "22.19.19",
|
||||
"@types/react": "19.2.14",
|
||||
"@types/react-dom": "19.2.3",
|
||||
"@vitejs/plugin-react": "6.0.2",
|
||||
"@vitejs/plugin-rsc": "0.5.26",
|
||||
"drizzle-kit": "0.31.10",
|
||||
"eslint": "9.39.4",
|
||||
"eslint-plugin-jsx-a11y": "6.10.2",
|
||||
"eslint-plugin-react": "7.37.5",
|
||||
"eslint-plugin-react-hooks": "7.1.1",
|
||||
"globals": "16.4.0",
|
||||
"react-server-dom-webpack": "19.2.6",
|
||||
"tailwindcss": "4.2.1",
|
||||
"typescript": "5.9.3",
|
||||
"typescript-eslint": "8.59.3",
|
||||
"vinext": "1.0.0-beta.2",
|
||||
"vite": "8.0.13",
|
||||
"wrangler": "4.92.0"
|
||||
},
|
||||
"type": "module"
|
||||
}
|
||||
@@ -0,0 +1,7 @@
|
||||
const config = {
|
||||
plugins: {
|
||||
"@tailwindcss/postcss": {},
|
||||
},
|
||||
};
|
||||
|
||||
export default config;
|
||||

@@ -0,0 +1,6 @@
|
||||
<svg width="24" height="24" viewBox="0 0 24 24" fill="none" xmlns="http://www.w3.org/2000/svg">
|
||||
<path d="M22 19.2727C22 20.779 20.779 22 19.2727 22H14.7273C13.221 22 12 20.779 12 19.2727V12H19.2727C20.779 12 22 13.221 22 14.7273V19.2727Z" fill="#68C4FF"/>
|
||||
<path d="M20 2C21.1046 2 22 2.89543 22 4V7C22 8.10457 21.1046 9 20 9H17C15.8954 9 15 8.10457 15 7V4C15 2.89543 15.8954 2 17 2H20Z" fill="#0C79D8"/>
|
||||
<path d="M7 15C8.10457 15 9 15.8954 9 17V20C9 21.1046 8.10457 22 7 22H4C2.89543 22 2 21.1046 2 20V17C2 15.8954 2.89543 15 4 15H7Z" fill="#0C79D8"/>
|
||||
<path d="M12 12H4.72727C3.22104 12 2 10.779 2 9.27273V4.72727C2 3.22104 3.22104 2 4.72727 2H9.27273C10.779 2 12 3.22104 12 4.72727V12Z" fill="#2E9EFF"/>
|
||||
</svg>
|
||||
|
After Width: | Height: | Size: 712 B |

@@ -0,0 +1 @@
|
||||
<svg fill="none" viewBox="0 0 16 16" xmlns="http://www.w3.org/2000/svg"><path d="M14.5 13.5V5.41a1 1 0 0 0-.3-.7L9.8.29A1 1 0 0 0 9.08 0H1.5v13.5A2.5 2.5 0 0 0 4 16h8a2.5 2.5 0 0 0 2.5-2.5m-1.5 0v-7H8v-5H3v12a1 1 0 0 0 1 1h8a1 1 0 0 0 1-1M9.5 5V2.12L12.38 5zM5.13 5h-.62v1.25h2.12V5zm-.62 3h7.12v1.25H4.5zm.62 3h-.62v1.25h7.12V11z" clip-rule="evenodd" fill="#666" fill-rule="evenodd"/></svg>
|
||||
|
After Width: | Height: | Size: 392 B |

@@ -0,0 +1 @@
|
||||
<svg fill="none" xmlns="http://www.w3.org/2000/svg" viewBox="0 0 16 16"><g clip-path="url(#a)"><path fill-rule="evenodd" clip-rule="evenodd" d="M10.27 14.1a6.5 6.5 0 0 0 3.67-3.45q-1.24.21-2.7.34-.31 1.83-.97 3.1M8 16A8 8 0 1 0 8 0a8 8 0 0 0 0 16m.48-1.52a7 7 0 0 1-.96 0H7.5a4 4 0 0 1-.84-1.32q-.38-.89-.63-2.08a40 40 0 0 0 3.92 0q-.25 1.2-.63 2.08a4 4 0 0 1-.84 1.31zm2.94-4.76q1.66-.15 2.95-.43a7 7 0 0 0 0-2.58q-1.3-.27-2.95-.43a18 18 0 0 1 0 3.44m-1.27-3.54a17 17 0 0 1 0 3.64 39 39 0 0 1-4.3 0 17 17 0 0 1 0-3.64 39 39 0 0 1 4.3 0m1.1-1.17q1.45.13 2.69.34a6.5 6.5 0 0 0-3.67-3.44q.65 1.26.98 3.1M8.48 1.5l.01.02q.41.37.84 1.31.38.89.63 2.08a40 40 0 0 0-3.92 0q.25-1.2.63-2.08a4 4 0 0 1 .85-1.32 7 7 0 0 1 .96 0m-2.75.4a6.5 6.5 0 0 0-3.67 3.44 29 29 0 0 1 2.7-.34q.31-1.83.97-3.1M4.58 6.28q-1.66.16-2.95.43a7 7 0 0 0 0 2.58q1.3.27 2.95.43a18 18 0 0 1 0-3.44m.17 4.71q-1.45-.12-2.69-.34a6.5 6.5 0 0 0 3.67 3.44q-.65-1.27-.98-3.1" fill="#666"/></g><defs><clipPath id="a"><path fill="#fff" d="M0 0h16v16H0z"/></clipPath></defs></svg>
|
||||
|
After Width: | Height: | Size: 1.0 KiB |

Binary file not shown.
|
After Width: | Height: | Size: 1.0 MiB |

@@ -0,0 +1 @@
|
||||
<svg fill="none" xmlns="http://www.w3.org/2000/svg" viewBox="0 0 16 16"><path fill-rule="evenodd" clip-rule="evenodd" d="M1.5 2.5h13v10a1 1 0 0 1-1 1h-11a1 1 0 0 1-1-1zM0 1h16v11.5a2.5 2.5 0 0 1-2.5 2.5h-11A2.5 2.5 0 0 1 0 12.5zm3.75 4.5a.75.75 0 1 0 0-1.5.75.75 0 0 0 0 1.5M7 4.75a.75.75 0 1 1-1.5 0 .75.75 0 0 1 1.5 0m1.75.75a.75.75 0 1 0 0-1.5.75.75 0 0 0 0 1.5" fill="#666"/></svg>
|
||||
|
After Width: | Height: | Size: 386 B |
@@ -0,0 +1,59 @@
|
||||
import assert from "node:assert/strict";
|
||||
import { readFile } from "node:fs/promises";
|
||||
import test from "node:test";
|
||||
|
||||
async function render() {
|
||||
const workerUrl = new URL("../dist/server/index.js", import.meta.url);
|
||||
workerUrl.searchParams.set("test", `${process.pid}-${Date.now()}`);
|
||||
const { default: worker } = await import(workerUrl.href);
|
||||
|
||||
return worker.fetch(
|
||||
new Request("http://localhost/", {
|
||||
headers: { accept: "text/html" },
|
||||
}),
|
||||
{ ASSETS: { fetch: async () => new Response("Not found", { status: 404 }) } },
|
||||
{ waitUntil() {}, passThroughOnException() {} },
|
||||
);
|
||||
}
|
||||
|
||||
test("server-renders the measured optimization matrix", async () => {
|
||||
const response = await render();
|
||||
assert.equal(response.status, 200);
|
||||
assert.match(response.headers.get("content-type") ?? "", /^text\/html\b/i);
|
||||
|
||||
const html = await response.text();
|
||||
assert.match(html, /VLM Speed Lab/);
|
||||
assert.match(html, /7\.33/);
|
||||
assert.match(html, /202\.6/);
|
||||
assert.match(html, /Source-resolution control/);
|
||||
assert.match(html, /Compiled execution/);
|
||||
assert.match(html, /Exact vs 01b/);
|
||||
assert.match(html, /Corrupt repeat/);
|
||||
assert.match(html, /SGLang 0\.5\.9 native/);
|
||||
assert.match(html, /Triton vision attention/);
|
||||
assert.match(html, /TensorRT \+ SGLang bridge/);
|
||||
assert.match(html, /Semantic · exact fail/);
|
||||
assert.match(html, /Invalid — gate failed/);
|
||||
assert.match(html, /88\.351s → 6\.858s/);
|
||||
assert.doesNotMatch(html, /GPU run pending|end-to-end run pending/);
|
||||
assert.doesNotMatch(html, /codex-preview|react-loading-skeleton/);
|
||||
});
|
||||
|
||||
test("keeps measured regressions visually honest", async () => {
|
||||
const [page, css] = await Promise.all([
|
||||
readFile(new URL("../app/page.tsx", import.meta.url), "utf8"),
|
||||
readFile(new URL("../app/globals.css", import.meta.url), "utf8"),
|
||||
]);
|
||||
|
||||
assert.match(page, /p50 \/ p95 ms/);
|
||||
assert.match(page, /Not measured/);
|
||||
assert.match(page, /status: "regression"/);
|
||||
assert.match(page, /status: "rejected"/);
|
||||
assert.match(page, /ttft: \["34\.9", "37\.8"\]/);
|
||||
assert.match(page, /4\/4 concepts/);
|
||||
assert.match(page, /Semantic preservation and exact bytes/);
|
||||
assert.match(css, /\.comparison-table-wrap \{ overflow-x:auto/);
|
||||
assert.match(css, /\.status-measured/);
|
||||
assert.match(css, /\.status-rejected/);
|
||||
assert.match(css, /\.status-planned/);
|
||||
});
|
||||
@@ -0,0 +1,29 @@
|
||||
{
|
||||
"compilerOptions": {
|
||||
"target": "ES2017",
|
||||
"lib": ["dom", "dom.iterable", "esnext"],
|
||||
"allowJs": true,
|
||||
"skipLibCheck": true,
|
||||
"strict": true,
|
||||
"noEmit": true,
|
||||
"esModuleInterop": true,
|
||||
"module": "esnext",
|
||||
"moduleResolution": "bundler",
|
||||
"resolveJsonModule": true,
|
||||
"isolatedModules": true,
|
||||
"jsx": "react-jsx",
|
||||
"incremental": true,
|
||||
"paths": {
|
||||
"@/*": ["./*"]
|
||||
}
|
||||
},
|
||||
"include": [
|
||||
"next-env.d.ts",
|
||||
"**/*.ts",
|
||||
"**/*.tsx",
|
||||
".next/types/**/*.ts",
|
||||
".next/dev/types/**/*.ts",
|
||||
"**/*.mts"
|
||||
],
|
||||
"exclude": ["node_modules"]
|
||||
}
|
||||
@@ -0,0 +1,59 @@
|
||||
import vinext from "vinext";
|
||||
import { defineConfig } from "vite";
|
||||
import hostingConfig from "./.openai/hosting.json";
|
||||
import { sites } from "./build/sites-vite-plugin";
|
||||
|
||||
const SITE_CREATOR_PLACEHOLDER_DATABASE_ID =
|
||||
"00000000-0000-4000-8000-000000000000";
|
||||
|
||||
const { d1, r2 } = hostingConfig;
|
||||
|
||||
// macOS Seatbelt blocks FSEvents, so Codex previews need polling for HMR.
|
||||
const isCodexSeatbeltSandbox = process.env.CODEX_SANDBOX === "seatbelt";
|
||||
|
||||
const localBindingConfig = {
|
||||
main: "./worker/index.ts",
|
||||
compatibility_flags: ["nodejs_compat"],
|
||||
d1_databases: d1
|
||||
? [
|
||||
{
|
||||
binding: d1,
|
||||
database_name: "site-creator-d1",
|
||||
database_id: SITE_CREATOR_PLACEHOLDER_DATABASE_ID,
|
||||
},
|
||||
]
|
||||
: [],
|
||||
r2_buckets: r2
|
||||
? [
|
||||
{
|
||||
binding: r2,
|
||||
bucket_name: "site-creator-r2",
|
||||
},
|
||||
]
|
||||
: [],
|
||||
};
|
||||
|
||||
export default defineConfig(async () => {
|
||||
// Keep Wrangler and Miniflare state project-local. These are non-secret tool
|
||||
// settings; application environment belongs in ignored `.env*` files.
|
||||
process.env.WRANGLER_WRITE_LOGS ??= "false";
|
||||
process.env.WRANGLER_LOG_PATH ??= ".wrangler/logs";
|
||||
process.env.MINIFLARE_REGISTRY_PATH ??= ".wrangler/registry";
|
||||
|
||||
// Wrangler snapshots its log path while the Cloudflare plugin is imported.
|
||||
const { cloudflare } = await import("@cloudflare/vite-plugin");
|
||||
|
||||
return {
|
||||
server: isCodexSeatbeltSandbox
|
||||
? { watch: { useFsEvents: false, usePolling: true } }
|
||||
: undefined,
|
||||
plugins: [
|
||||
vinext(),
|
||||
sites(),
|
||||
cloudflare({
|
||||
viteEnvironment: { name: "rsc", childEnvironments: ["ssr"] },
|
||||
config: localBindingConfig,
|
||||
}),
|
||||
],
|
||||
};
|
||||
});
|
||||
@@ -0,0 +1,47 @@
|
||||
/** Cloudflare Worker entry point for the vinext-starter template. */
|
||||
import { handleImageOptimization, DEFAULT_DEVICE_SIZES, DEFAULT_IMAGE_SIZES } from "vinext/server/image-optimization";
|
||||
import handler from "vinext/server/app-router-entry";
|
||||
|
||||
interface Env {
|
||||
ASSETS: Fetcher;
|
||||
DB: D1Database;
|
||||
IMAGES: {
|
||||
input(stream: ReadableStream): {
|
||||
transform(options: Record<string, unknown>): {
|
||||
output(options: { format: string; quality: number }): Promise<{ response(): Response }>;
|
||||
};
|
||||
};
|
||||
};
|
||||
}
|
||||
|
||||
interface ExecutionContext {
|
||||
waitUntil(promise: Promise<unknown>): void;
|
||||
passThroughOnException(): void;
|
||||
}
|
||||
|
||||
// Image security config. SVG sources with .svg extension auto-skip the
|
||||
// optimization endpoint on the client side (served directly, no proxy).
|
||||
// To route SVGs through the optimizer (with security headers), set
|
||||
// dangerouslyAllowSVG: true in next.config.js and uncomment below:
|
||||
// const imageConfig: ImageConfig = { dangerouslyAllowSVG: true };
|
||||
|
||||
const worker = {
|
||||
async fetch(request: Request, env: Env, ctx: ExecutionContext): Promise<Response> {
|
||||
const url = new URL(request.url);
|
||||
|
||||
if (url.pathname === "/_vinext/image") {
|
||||
const allowedWidths = [...DEFAULT_DEVICE_SIZES, ...DEFAULT_IMAGE_SIZES];
|
||||
return handleImageOptimization(request, {
|
||||
fetchAsset: (path) => env.ASSETS.fetch(new Request(new URL(path, request.url))),
|
||||
transformImage: async (body, { width, format, quality }) => {
|
||||
const result = await env.IMAGES.input(body).transform(width > 0 ? { width } : {}).output({ format, quality });
|
||||
return result.response();
|
||||
},
|
||||
}, allowedWidths);
|
||||
}
|
||||
|
||||
return handler.fetch(request, env, ctx);
|
||||
},
|
||||
};
|
||||
|
||||
export default worker;
|
||||
@@ -0,0 +1,34 @@
|
||||
{
|
||||
"name": "qwen3-vl-2b-control-v1",
|
||||
"model": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"max_tokens": 128,
|
||||
"temperature": 0.0,
|
||||
"quality_tolerance": 0.98,
|
||||
"cases": [
|
||||
{
|
||||
"id": "caption-001",
|
||||
"task": "caption",
|
||||
"image": "media/caption-001.jpg",
|
||||
"prompt": "Describe the image in one precise sentence.",
|
||||
"evaluator": "keywords",
|
||||
"expected": ["replace", "with", "ground-truth", "keywords"]
|
||||
},
|
||||
{
|
||||
"id": "ocr-001",
|
||||
"task": "ocr",
|
||||
"image": "media/ocr-001.png",
|
||||
"prompt": "Return only the text visible in the image.",
|
||||
"evaluator": "exact",
|
||||
"expected": "REPLACE WITH GROUND TRUTH"
|
||||
},
|
||||
{
|
||||
"id": "count-001",
|
||||
"task": "count",
|
||||
"image": "media/count-001.png",
|
||||
"prompt": "How many red objects are visible? Return only the integer.",
|
||||
"evaluator": "number",
|
||||
"expected": 0
|
||||
}
|
||||
]
|
||||
}
|
||||
|
||||
@@ -0,0 +1,23 @@
|
||||
{
|
||||
"name": "qwen3-vl-2b-demo-448-v1",
|
||||
"model": "Qwen/Qwen3-VL-2B-Instruct",
|
||||
"max_tokens": 96,
|
||||
"temperature": 0.0,
|
||||
"quality_tolerance": 1.0,
|
||||
"cases": [
|
||||
{
|
||||
"id": "caption-qwen-demo-001",
|
||||
"task": "caption",
|
||||
"image": "media/qwen-demo.jpeg",
|
||||
"longest_edge": 448,
|
||||
"prompt": "Describe this image precisely in one sentence.",
|
||||
"evaluator": "concepts",
|
||||
"expected": [
|
||||
["woman"],
|
||||
["golden retriever"],
|
||||
["beach"],
|
||||
["high-five", "high-fiving", "high five", "high fiving"]
|
||||
]
|
||||
}
|
||||
]
|
||||
}
|
||||
@@ -0,0 +1,310 @@
|
||||
"""Quality-gated benchmark for OpenAI-compatible VLM servers.
|
||||
|
||||
The runner intentionally depends only on packages already required by this
|
||||
repository. It is suitable for SGLang and TensorRT-LLM chat endpoints and keeps
|
||||
the raw evidence required to audit every aggregate number.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import base64
|
||||
import hashlib
|
||||
import io
|
||||
import json
|
||||
import math
|
||||
import mimetypes
|
||||
import platform
|
||||
import re
|
||||
import statistics
|
||||
import subprocess
|
||||
import time
|
||||
from datetime import UTC, datetime
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
import httpx
|
||||
from PIL import Image
|
||||
|
||||
|
||||
def normalize_text(value: str) -> str:
|
||||
return " ".join(re.sub(r"[^\w\s]", " ", value.casefold()).split())
|
||||
|
||||
|
||||
def score_output(output: str, evaluator: str, expected: Any) -> float:
|
||||
normalized = normalize_text(output)
|
||||
if evaluator == "exact":
|
||||
return float(normalized == normalize_text(str(expected)))
|
||||
if evaluator == "keywords":
|
||||
terms = [normalize_text(str(term)) for term in expected]
|
||||
terms = [term for term in terms if term]
|
||||
return sum(term in normalized for term in terms) / len(terms) if terms else 0.0
|
||||
if evaluator == "concepts":
|
||||
concepts = []
|
||||
for concept in expected:
|
||||
aliases = concept if isinstance(concept, list) else [concept]
|
||||
aliases = [normalize_text(str(alias)) for alias in aliases]
|
||||
aliases = [alias for alias in aliases if alias]
|
||||
if aliases:
|
||||
concepts.append(aliases)
|
||||
return (
|
||||
sum(any(alias in normalized for alias in aliases) for aliases in concepts)
|
||||
/ len(concepts)
|
||||
if concepts
|
||||
else 0.0
|
||||
)
|
||||
if evaluator == "number":
|
||||
match = re.search(r"-?\d+", output.replace(",", ""))
|
||||
return float(match is not None and int(match.group()) == int(expected))
|
||||
raise ValueError(f"Unsupported evaluator: {evaluator!r}")
|
||||
|
||||
|
||||
def percentile(values: list[float], quantile: float) -> float:
|
||||
if not values:
|
||||
return math.nan
|
||||
ordered = sorted(values)
|
||||
position = (len(ordered) - 1) * quantile
|
||||
lower = math.floor(position)
|
||||
upper = math.ceil(position)
|
||||
if lower == upper:
|
||||
return ordered[lower]
|
||||
return ordered[lower] * (upper - position) + ordered[upper] * (position - lower)
|
||||
|
||||
|
||||
def file_data_url(path: Path, longest_edge: int | None) -> tuple[str, str, dict]:
|
||||
content = path.read_bytes()
|
||||
source_digest = hashlib.sha256(content).hexdigest()
|
||||
image = Image.open(io.BytesIO(content)).convert("RGB")
|
||||
source_size = image.size
|
||||
if longest_edge is not None and max(image.size) > longest_edge:
|
||||
scale = longest_edge / max(image.size)
|
||||
image = image.resize(
|
||||
(round(image.width * scale), round(image.height * scale)),
|
||||
Image.Resampling.BOX,
|
||||
)
|
||||
buffer = io.BytesIO()
|
||||
image.save(buffer, format="PNG")
|
||||
content = buffer.getvalue()
|
||||
mime = "image/png"
|
||||
else:
|
||||
mime = mimetypes.guess_type(path.name)[0] or "application/octet-stream"
|
||||
encoded = base64.b64encode(content).decode("ascii")
|
||||
return (
|
||||
f"data:{mime};base64,{encoded}",
|
||||
hashlib.sha256(content).hexdigest(),
|
||||
{
|
||||
"source_sha256": source_digest,
|
||||
"source_width": source_size[0],
|
||||
"source_height": source_size[1],
|
||||
"processed_width": image.width,
|
||||
"processed_height": image.height,
|
||||
},
|
||||
)
|
||||
|
||||
|
||||
def git_value(*args: str) -> str | None:
|
||||
try:
|
||||
return subprocess.check_output(
|
||||
["git", *args], text=True, stderr=subprocess.DEVNULL
|
||||
).strip()
|
||||
except (OSError, subprocess.CalledProcessError):
|
||||
return None
|
||||
|
||||
|
||||
def parse_sse_line(line: str) -> dict[str, Any] | None:
|
||||
if not line.startswith("data:"):
|
||||
return None
|
||||
payload = line[5:].strip()
|
||||
if not payload or payload == "[DONE]":
|
||||
return None
|
||||
return json.loads(payload)
|
||||
|
||||
|
||||
def run_request(
|
||||
client: httpx.Client,
|
||||
*,
|
||||
base_url: str,
|
||||
model: str,
|
||||
prompt: str,
|
||||
image_url: str,
|
||||
max_tokens: int,
|
||||
temperature: float,
|
||||
) -> dict[str, Any]:
|
||||
payload = {
|
||||
"model": model,
|
||||
"messages": [
|
||||
{
|
||||
"role": "user",
|
||||
"content": [
|
||||
{"type": "image_url", "image_url": {"url": image_url}},
|
||||
{"type": "text", "text": prompt},
|
||||
],
|
||||
}
|
||||
],
|
||||
"max_tokens": max_tokens,
|
||||
"temperature": temperature,
|
||||
"stream": True,
|
||||
"stream_options": {"include_usage": True},
|
||||
}
|
||||
started = time.perf_counter()
|
||||
first_content_at: float | None = None
|
||||
pieces: list[str] = []
|
||||
usage: dict[str, Any] = {}
|
||||
with client.stream(
|
||||
"POST", f"{base_url.rstrip('/')}/chat/completions", json=payload
|
||||
) as response:
|
||||
response.raise_for_status()
|
||||
for line in response.iter_lines():
|
||||
event = parse_sse_line(line)
|
||||
if event is None:
|
||||
continue
|
||||
usage = event.get("usage") or usage
|
||||
for choice in event.get("choices", []):
|
||||
content = (choice.get("delta") or {}).get("content")
|
||||
if content:
|
||||
if first_content_at is None:
|
||||
first_content_at = time.perf_counter()
|
||||
pieces.append(content)
|
||||
finished = time.perf_counter()
|
||||
output = "".join(pieces)
|
||||
completion_tokens = usage.get("completion_tokens")
|
||||
decode_seconds = finished - (first_content_at or finished)
|
||||
return {
|
||||
"output": output,
|
||||
"latency_ms": round((finished - started) * 1000, 3),
|
||||
"ttft_ms": round(((first_content_at or finished) - started) * 1000, 3),
|
||||
"completion_tokens": completion_tokens,
|
||||
"output_tokens_per_second": (
|
||||
round(completion_tokens / decode_seconds, 3)
|
||||
if completion_tokens and decode_seconds > 0
|
||||
else None
|
||||
),
|
||||
"usage": usage,
|
||||
}
|
||||
|
||||
|
||||
def aggregate(samples: list[dict[str, Any]]) -> dict[str, Any]:
|
||||
latencies = [float(sample["latency_ms"]) for sample in samples]
|
||||
ttfts = [float(sample["ttft_ms"]) for sample in samples]
|
||||
rates = [
|
||||
float(sample["output_tokens_per_second"])
|
||||
for sample in samples
|
||||
if sample.get("output_tokens_per_second") is not None
|
||||
]
|
||||
return {
|
||||
"requests": len(samples),
|
||||
"latency_ms": {
|
||||
"p50": round(percentile(latencies, 0.50), 3),
|
||||
"p95": round(percentile(latencies, 0.95), 3),
|
||||
"p99": round(percentile(latencies, 0.99), 3),
|
||||
},
|
||||
"ttft_ms": {
|
||||
"p50": round(percentile(ttfts, 0.50), 3),
|
||||
"p95": round(percentile(ttfts, 0.95), 3),
|
||||
"p99": round(percentile(ttfts, 0.99), 3),
|
||||
},
|
||||
"output_tokens_per_second_mean": round(statistics.fmean(rates), 3) if rates else None,
|
||||
"quality_mean": round(statistics.fmean(sample["quality"] for sample in samples), 6),
|
||||
}
|
||||
|
||||
|
||||
def main() -> None:
|
||||
parser = argparse.ArgumentParser(description=__doc__)
|
||||
parser.add_argument("--suite", type=Path, required=True)
|
||||
parser.add_argument("--base-url", required=True)
|
||||
parser.add_argument("--backend", choices=("sglang", "tensorrt-llm", "other"), required=True)
|
||||
parser.add_argument("--label", required=True)
|
||||
parser.add_argument("--warmups", type=int, default=3)
|
||||
parser.add_argument("--runs", type=int, default=30)
|
||||
parser.add_argument("--timeout", type=float, default=180.0)
|
||||
parser.add_argument("--output-dir", type=Path, default=Path("benchmarks/results"))
|
||||
args = parser.parse_args()
|
||||
if args.warmups < 0 or args.runs < 1:
|
||||
parser.error("--warmups must be non-negative and --runs must be positive")
|
||||
|
||||
suite_path = args.suite.resolve()
|
||||
suite = json.loads(suite_path.read_text(encoding="utf-8"))
|
||||
cases = suite.get("cases") or []
|
||||
if not cases:
|
||||
raise ValueError("The suite must contain at least one case.")
|
||||
|
||||
prepared = []
|
||||
for case in cases:
|
||||
media_path = (suite_path.parent / case["image"]).resolve()
|
||||
if not media_path.is_file():
|
||||
raise FileNotFoundError(f"Missing benchmark media: {media_path}")
|
||||
data_url, digest, media = file_data_url(
|
||||
media_path,
|
||||
int(case["longest_edge"]) if case.get("longest_edge") else None,
|
||||
)
|
||||
prepared.append((case, data_url, digest, media))
|
||||
|
||||
samples: list[dict[str, Any]] = []
|
||||
with httpx.Client(timeout=args.timeout) as client:
|
||||
for index in range(args.warmups + args.runs):
|
||||
case, data_url, digest, media = prepared[index % len(prepared)]
|
||||
result = run_request(
|
||||
client,
|
||||
base_url=args.base_url,
|
||||
model=suite["model"],
|
||||
prompt=case["prompt"],
|
||||
image_url=data_url,
|
||||
max_tokens=int(suite.get("max_tokens", 128)),
|
||||
temperature=float(suite.get("temperature", 0.0)),
|
||||
)
|
||||
if index < args.warmups:
|
||||
continue
|
||||
result.update(
|
||||
{
|
||||
"sample": index - args.warmups,
|
||||
"case_id": case["id"],
|
||||
"task": case["task"],
|
||||
"media_sha256": digest,
|
||||
"media": media,
|
||||
"quality": score_output(
|
||||
result["output"], case["evaluator"], case["expected"]
|
||||
),
|
||||
}
|
||||
)
|
||||
samples.append(result)
|
||||
|
||||
summary = aggregate(samples)
|
||||
tolerance = float(suite.get("quality_tolerance", 0.98))
|
||||
artifact = {
|
||||
"schema": "comfyui-vlm/benchmark-run",
|
||||
"version": 1,
|
||||
"created_at": datetime.now(UTC).isoformat(),
|
||||
"label": args.label,
|
||||
"backend": args.backend,
|
||||
"suite": suite["name"],
|
||||
"model": suite["model"],
|
||||
"git_commit": git_value("rev-parse", "HEAD"),
|
||||
"git_dirty": bool(git_value("status", "--porcelain")),
|
||||
"environment": {
|
||||
"platform": platform.platform(),
|
||||
"python": platform.python_version(),
|
||||
"server_base_url": args.base_url,
|
||||
},
|
||||
"settings": {
|
||||
"warmups": args.warmups,
|
||||
"runs": args.runs,
|
||||
"max_tokens": suite.get("max_tokens", 128),
|
||||
"temperature": suite.get("temperature", 0.0),
|
||||
"quality_tolerance": tolerance,
|
||||
},
|
||||
"summary": summary,
|
||||
"quality_gate": {
|
||||
"threshold": tolerance,
|
||||
"passed": summary["quality_mean"] >= tolerance,
|
||||
},
|
||||
"samples": samples,
|
||||
}
|
||||
args.output_dir.mkdir(parents=True, exist_ok=True)
|
||||
timestamp = datetime.now(UTC).strftime("%Y%m%dT%H%M%SZ")
|
||||
output = args.output_dir / f"{timestamp}-{args.label}.json"
|
||||
output.write_text(json.dumps(artifact, ensure_ascii=False, indent=2) + "\n", encoding="utf-8")
|
||||
print(output)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -1,5 +0,0 @@
|
||||
llama-cpp-agent
|
||||
mkdocs
|
||||
mkdocs-material
|
||||
mkdocstrings[python]
|
||||
docstring-parser
|
||||
@@ -0,0 +1,690 @@
|
||||
{
|
||||
"last_node_id": 43,
|
||||
"last_link_id": 54,
|
||||
"nodes": [
|
||||
{
|
||||
"id": 31,
|
||||
"type": "LlavaClipLoader",
|
||||
"pos": [
|
||||
439.6340175903321,
|
||||
172.3240056098938
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 58
|
||||
},
|
||||
"flags": {},
|
||||
"order": 0,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "clip",
|
||||
"type": "CUSTOM",
|
||||
"links": [
|
||||
37
|
||||
],
|
||||
"shape": 3
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LlavaClipLoader"
|
||||
},
|
||||
"widgets_values": [
|
||||
"mistrallava16clip.gguf"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 35,
|
||||
"type": "SimpleText",
|
||||
"pos": [
|
||||
1145.0176354455555,
|
||||
158.27893214202888
|
||||
],
|
||||
"size": {
|
||||
"0": 378.79046630859375,
|
||||
"1": 186.27911376953125
|
||||
},
|
||||
"flags": {},
|
||||
"order": 1,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "STRING",
|
||||
"type": "STRING",
|
||||
"links": [
|
||||
41
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "SimpleText"
|
||||
},
|
||||
"widgets_values": [
|
||||
"You are an advanced AI that shortens descriptions into sentences.\n\nExample 1: Birds singing sweetly in a blooming garden\nExample 2: A modern synthesizer creating futuristic soundscapes\nExample 3: The vibrant beat of Brazilian samba drums"
|
||||
],
|
||||
"color": "#232",
|
||||
"bgcolor": "#353"
|
||||
},
|
||||
{
|
||||
"id": 32,
|
||||
"type": "SimpleText",
|
||||
"pos": [
|
||||
439.6340175903321,
|
||||
452.3240056098937
|
||||
],
|
||||
"size": {
|
||||
"0": 318.79754638671875,
|
||||
"1": 82.05603790283203
|
||||
},
|
||||
"flags": {},
|
||||
"order": 2,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "STRING",
|
||||
"type": "STRING",
|
||||
"links": [
|
||||
38
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "SimpleText"
|
||||
},
|
||||
"widgets_values": [
|
||||
"describe this image in short, concisely"
|
||||
],
|
||||
"color": "#232",
|
||||
"bgcolor": "#353"
|
||||
},
|
||||
{
|
||||
"id": 38,
|
||||
"type": "SimpleText",
|
||||
"pos": [
|
||||
647.6433994140625,
|
||||
1010.9179632824712
|
||||
],
|
||||
"size": {
|
||||
"0": 318.79754638671875,
|
||||
"1": 82.05603790283203
|
||||
},
|
||||
"flags": {},
|
||||
"order": 3,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "STRING",
|
||||
"type": "STRING",
|
||||
"links": [
|
||||
45
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "SimpleText"
|
||||
},
|
||||
"widgets_values": [
|
||||
"Low quality, average quality."
|
||||
],
|
||||
"color": "#322",
|
||||
"bgcolor": "#533"
|
||||
},
|
||||
{
|
||||
"id": 29,
|
||||
"type": "LLavaSamplerSimple",
|
||||
"pos": [
|
||||
769.6340175903323,
|
||||
182.3240056098938
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 102
|
||||
},
|
||||
"flags": {},
|
||||
"order": 6,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "image",
|
||||
"type": "IMAGE",
|
||||
"link": 39,
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "model",
|
||||
"type": "CUSTOM",
|
||||
"link": 36,
|
||||
"slot_index": 1
|
||||
},
|
||||
{
|
||||
"name": "prompt",
|
||||
"type": "STRING",
|
||||
"link": 38,
|
||||
"widget": {
|
||||
"name": "prompt"
|
||||
},
|
||||
"slot_index": 2
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "STRING",
|
||||
"type": "STRING",
|
||||
"links": [
|
||||
42,
|
||||
43
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LLavaSamplerSimple"
|
||||
},
|
||||
"widgets_values": [
|
||||
"",
|
||||
0.1
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 36,
|
||||
"type": "ViewText",
|
||||
"pos": [
|
||||
774,
|
||||
325
|
||||
],
|
||||
"size": {
|
||||
"0": 303.2503967285156,
|
||||
"1": 156.48916625976562
|
||||
},
|
||||
"flags": {},
|
||||
"order": 8,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "text",
|
||||
"type": "STRING",
|
||||
"link": 43,
|
||||
"widget": {
|
||||
"name": "text"
|
||||
}
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "STRING",
|
||||
"type": "STRING",
|
||||
"links": null,
|
||||
"shape": 3
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "ViewText"
|
||||
},
|
||||
"widgets_values": [
|
||||
"",
|
||||
" The image shows a group of dancers performing on stage. They are dressed in colorful costumes with vibrant patterns and shades of green, yellow, and pink. The dancers appear to be in motion, suggesting they are dancing. The lighting is dim, which highlights the performers and creates a dramatic atmosphere. There is no visible text or branding in the image. The style of the image is a candid photograph capturing a live performance. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 30,
|
||||
"type": "LLava Loader Simple",
|
||||
"pos": [
|
||||
439.6340175903321,
|
||||
272.3240056098937
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 130
|
||||
},
|
||||
"flags": {},
|
||||
"order": 5,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "clip",
|
||||
"type": "CUSTOM",
|
||||
"link": 37,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "model",
|
||||
"type": "CUSTOM",
|
||||
"links": [
|
||||
36,
|
||||
40
|
||||
],
|
||||
"shape": 3
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LLava Loader Simple"
|
||||
},
|
||||
"widgets_values": [
|
||||
"llava-v1.6-mistral-7b.Q5_K_M.gguf",
|
||||
2048,
|
||||
100,
|
||||
2
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 33,
|
||||
"type": "LoadImage",
|
||||
"pos": [
|
||||
100,
|
||||
172
|
||||
],
|
||||
"size": {
|
||||
"0": 328.0104675292969,
|
||||
"1": 361.09918212890625
|
||||
},
|
||||
"flags": {},
|
||||
"order": 4,
|
||||
"mode": 0,
|
||||
"outputs": [
|
||||
{
|
||||
"name": "IMAGE",
|
||||
"type": "IMAGE",
|
||||
"links": [
|
||||
39
|
||||
],
|
||||
"shape": 3
|
||||
},
|
||||
{
|
||||
"name": "MASK",
|
||||
"type": "MASK",
|
||||
"links": null,
|
||||
"shape": 3
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LoadImage"
|
||||
},
|
||||
"widgets_values": [
|
||||
"412342132.PNG",
|
||||
"image"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 34,
|
||||
"type": "LLMSampler",
|
||||
"pos": [
|
||||
1536,
|
||||
193
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 298
|
||||
},
|
||||
"flags": {},
|
||||
"order": 7,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "model",
|
||||
"type": "CUSTOM",
|
||||
"link": 40,
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "prompt",
|
||||
"type": "STRING",
|
||||
"link": 42,
|
||||
"widget": {
|
||||
"name": "prompt"
|
||||
},
|
||||
"slot_index": 1
|
||||
},
|
||||
{
|
||||
"name": "system_msg",
|
||||
"type": "STRING",
|
||||
"link": 41,
|
||||
"widget": {
|
||||
"name": "system_msg"
|
||||
}
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "STRING",
|
||||
"type": "STRING",
|
||||
"links": [
|
||||
44,
|
||||
48
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "LLMSampler"
|
||||
},
|
||||
"widgets_values": [
|
||||
"You are an assistant who perfectly describes images.",
|
||||
"",
|
||||
512,
|
||||
0.1,
|
||||
0.95,
|
||||
40,
|
||||
0,
|
||||
0,
|
||||
1.1,
|
||||
617,
|
||||
"randomize"
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 40,
|
||||
"type": "ViewText",
|
||||
"pos": [
|
||||
1162,
|
||||
399
|
||||
],
|
||||
"size": {
|
||||
"0": 345.2934265136719,
|
||||
"1": 106.57048034667969
|
||||
},
|
||||
"flags": {},
|
||||
"order": 10,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "text",
|
||||
"type": "STRING",
|
||||
"link": 48,
|
||||
"widget": {
|
||||
"name": "text"
|
||||
}
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "STRING",
|
||||
"type": "STRING",
|
||||
"links": null,
|
||||
"shape": 3
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "ViewText"
|
||||
},
|
||||
"widgets_values": [
|
||||
"",
|
||||
" Dancers in colorful costumes performing on stage under dim lighting. "
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 43,
|
||||
"type": "PlayMusic",
|
||||
"pos": [
|
||||
1033,
|
||||
720
|
||||
],
|
||||
"size": [
|
||||
315,
|
||||
130
|
||||
],
|
||||
"flags": {},
|
||||
"order": 11,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "wave_form",
|
||||
"type": "COMBO",
|
||||
"link": 53,
|
||||
"widget": {
|
||||
"name": "wave_form"
|
||||
}
|
||||
},
|
||||
{
|
||||
"name": "sample_rate",
|
||||
"type": "INT",
|
||||
"link": 54,
|
||||
"widget": {
|
||||
"name": "sample_rate"
|
||||
}
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "*",
|
||||
"type": "*",
|
||||
"links": null,
|
||||
"shape": 6
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "PlayMusic"
|
||||
},
|
||||
"widgets_values": [
|
||||
"always",
|
||||
0.5,
|
||||
null,
|
||||
0
|
||||
]
|
||||
},
|
||||
{
|
||||
"id": 37,
|
||||
"type": "AudioLDM2Node",
|
||||
"pos": [
|
||||
666,
|
||||
725
|
||||
],
|
||||
"size": {
|
||||
"0": 315,
|
||||
"1": 222
|
||||
},
|
||||
"flags": {},
|
||||
"order": 9,
|
||||
"mode": 0,
|
||||
"inputs": [
|
||||
{
|
||||
"name": "text",
|
||||
"type": "STRING",
|
||||
"link": 44,
|
||||
"widget": {
|
||||
"name": "text"
|
||||
}
|
||||
},
|
||||
{
|
||||
"name": "negative_prompt",
|
||||
"type": "STRING",
|
||||
"link": 45,
|
||||
"widget": {
|
||||
"name": "negative_prompt"
|
||||
},
|
||||
"slot_index": 1
|
||||
}
|
||||
],
|
||||
"outputs": [
|
||||
{
|
||||
"name": "wave_form",
|
||||
"type": "*",
|
||||
"links": [
|
||||
53
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 0
|
||||
},
|
||||
{
|
||||
"name": "sample_rate",
|
||||
"type": "INT",
|
||||
"links": [
|
||||
54
|
||||
],
|
||||
"shape": 3,
|
||||
"slot_index": 1
|
||||
}
|
||||
],
|
||||
"properties": {
|
||||
"Node name for S&R": "AudioLDM2Node"
|
||||
},
|
||||
"widgets_values": [
|
||||
"",
|
||||
"",
|
||||
10,
|
||||
3.5,
|
||||
995,
|
||||
"randomize",
|
||||
3,
|
||||
16000,
|
||||
"mp3"
|
||||
]
|
||||
}
|
||||
],
|
||||
"links": [
|
||||
[
|
||||
36,
|
||||
30,
|
||||
0,
|
||||
29,
|
||||
1,
|
||||
"CUSTOM"
|
||||
],
|
||||
[
|
||||
37,
|
||||
31,
|
||||
0,
|
||||
30,
|
||||
0,
|
||||
"CUSTOM"
|
||||
],
|
||||
[
|
||||
38,
|
||||
32,
|
||||
0,
|
||||
29,
|
||||
2,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
39,
|
||||
33,
|
||||
0,
|
||||
29,
|
||||
0,
|
||||
"IMAGE"
|
||||
],
|
||||
[
|
||||
40,
|
||||
30,
|
||||
0,
|
||||
34,
|
||||
0,
|
||||
"CUSTOM"
|
||||
],
|
||||
[
|
||||
41,
|
||||
35,
|
||||
0,
|
||||
34,
|
||||
2,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
42,
|
||||
29,
|
||||
0,
|
||||
34,
|
||||
1,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
43,
|
||||
29,
|
||||
0,
|
||||
36,
|
||||
0,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
44,
|
||||
34,
|
||||
0,
|
||||
37,
|
||||
0,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
45,
|
||||
38,
|
||||
0,
|
||||
37,
|
||||
1,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
48,
|
||||
34,
|
||||
0,
|
||||
40,
|
||||
0,
|
||||
"STRING"
|
||||
],
|
||||
[
|
||||
53,
|
||||
37,
|
||||
0,
|
||||
43,
|
||||
0,
|
||||
"COMBO"
|
||||
],
|
||||
[
|
||||
54,
|
||||
37,
|
||||
1,
|
||||
43,
|
||||
1,
|
||||
"INT"
|
||||
]
|
||||
],
|
||||
"groups": [
|
||||
{
|
||||
"title": "VLM",
|
||||
"bounding": [
|
||||
90,
|
||||
98,
|
||||
1005,
|
||||
446
|
||||
],
|
||||
"color": "#3f789e",
|
||||
"font_size": 24,
|
||||
"locked": false
|
||||
},
|
||||
{
|
||||
"title": "LLM",
|
||||
"bounding": [
|
||||
1135,
|
||||
84,
|
||||
733,
|
||||
491
|
||||
],
|
||||
"color": "#a1309b",
|
||||
"font_size": 24,
|
||||
"locked": false
|
||||
},
|
||||
{
|
||||
"title": "Sound",
|
||||
"bounding": [
|
||||
638,
|
||||
667,
|
||||
711,
|
||||
436
|
||||
],
|
||||
"color": "#b58b2a",
|
||||
"font_size": 24,
|
||||
"locked": false
|
||||
}
|
||||
],
|
||||
"config": {},
|
||||
"extra": {},
|
||||
"version": 0.4
|
||||
}
|
||||
@@ -0,0 +1,266 @@
|
||||
# Robotics and VLA workflows
|
||||
|
||||
The robotics nodes make ComfyUI a policy-development, inspection, and
|
||||
simulation surface. They do **not** send commands to motors, ROS, CAN, serial,
|
||||
or a robot SDK.
|
||||
|
||||
The boundary is intentional:
|
||||
|
||||
```text
|
||||
camera/state/task
|
||||
|
|
||||
v
|
||||
VLA Observation Builder
|
||||
|
|
||||
v
|
||||
isolated policy server ---> raw action chunk
|
||||
|
|
||||
v
|
||||
VLA Action Safety Gate
|
||||
|
|
||||
+-------------+-------------+
|
||||
| |
|
||||
v v
|
||||
inspect / plot / record simulator or your own
|
||||
supervised controller bridge
|
||||
```
|
||||
|
||||
A real controller bridge must independently enforce a deadman, watchdog,
|
||||
emergency stop, collision/workspace limits, timestamps, command freshness, and
|
||||
the manufacturer's limits. A `safe_for_handoff=true` workflow result only
|
||||
means that the declared ComfyUI profile checks passed.
|
||||
|
||||
## Why policy runtimes are isolated
|
||||
|
||||
LeRobot, openpi, Isaac-GR00T, OpenVLA/OFT, and Octo use different PyTorch/JAX,
|
||||
CUDA, Transformers, compiler, and operating-system combinations. Installing
|
||||
all of those into ComfyUI would replace or constrain the working accelerator
|
||||
stack and make Windows, macOS, ROCm, and XPU support worse.
|
||||
|
||||
The ComfyUI package therefore contains only:
|
||||
|
||||
- typed state/action/camera contracts;
|
||||
- bounded image serialization;
|
||||
- a dependency-light universal HTTPS/loopback HTTP client;
|
||||
- exact clients for the official openpi MessagePack WebSocket and GR00T
|
||||
MessagePack/ZeroMQ protocols;
|
||||
- action validation, horizon control, inspection, and plotting.
|
||||
|
||||
The heavyweight policy stays in its own process, container, WSL distribution,
|
||||
Linux machine, Mac, or GPU server. This also allows ComfyUI to use AMD ROCm,
|
||||
Apple Metal, Intel XPU, or CPU while a policy runs on an NVIDIA Linux server.
|
||||
|
||||
## Fast path: SmolVLA through the universal sidecar
|
||||
|
||||
Use a separate LeRobot environment. Current LeRobot documentation recommends
|
||||
Python 3.12 and exposes policy-specific extras. On this computer, keep it on
|
||||
the D drive:
|
||||
|
||||
```bash
|
||||
# WSL
|
||||
python3.12 -m venv /mnt/d/vla-runtime/lerobot-smolvla
|
||||
source /mnt/d/vla-runtime/lerobot-smolvla/bin/activate
|
||||
python -m pip install --upgrade pip
|
||||
python -m pip install "lerobot[smolvla]"
|
||||
|
||||
export VLA_POLICY_TOKEN="$(python -c 'import secrets; print(secrets.token_urlsafe(32))')"
|
||||
python /mnt/d/ComfyUI_windows_portable/ComfyUI/custom_nodes/ComfyUI_VLM_nodes/examples/robotics/lerobot_policy_server.py \
|
||||
--policy-type smolvla \
|
||||
--policy-path YOUR_FINE_TUNED_SMOLVLA_CHECKPOINT \
|
||||
--device auto \
|
||||
--actions-per-chunk 16 \
|
||||
--idle-offload-seconds 300
|
||||
```
|
||||
|
||||
Set the same `VLA_POLICY_TOKEN` in the environment that launches ComfyUI.
|
||||
Never put it in a workflow. In `VLA Policy — Universal HTTP`, use
|
||||
`http://127.0.0.1:8787`.
|
||||
|
||||
`lerobot/smolvla_base` is a base model. It is a useful fine-tuning starting
|
||||
point, not a universal zero-shot controller. Use an embodiment-specific
|
||||
checkpoint whose feature names, action dimensions, state dimensions,
|
||||
normalization statistics, and camera keys match the workflow.
|
||||
|
||||
The sidecar:
|
||||
|
||||
- loads only the chosen policy and its serialized pre/post-processors;
|
||||
- uses `predict_action_chunk` when provided and falls back to `select_action`;
|
||||
- keeps the model resident by default for low latency;
|
||||
- can move it to CPU after an idle interval and move it back on demand;
|
||||
- accepts one request at a time per policy, preventing stateful policy races;
|
||||
- uses bounded JSON/JPEG rather than pickle;
|
||||
- never returns tracebacks, environment variables, request data, or
|
||||
authorization headers.
|
||||
|
||||
For a real local API acceptance run, start ComfyUI and the policy sidecar, put
|
||||
an image in ComfyUI's `input` directory, then run:
|
||||
|
||||
```bash
|
||||
python tests/manual_robotics_smoke.py \
|
||||
--comfy-url http://127.0.0.1:8188 \
|
||||
--policy-url http://127.0.0.1:8787 \
|
||||
--image robot_front.png
|
||||
```
|
||||
|
||||
The script queues the graph through `POST /prompt`, waits on its history entry,
|
||||
and prints the policy report, safety report, first action, and preview filename.
|
||||
|
||||
Install the relevant official LeRobot extra for another policy. Examples are
|
||||
`lerobot[pi]` for π0/π0.5/π0-FAST and `lerobot[smolvla]` for SmolVLA. Some
|
||||
newer policy integrations may require installing current LeRobot from source
|
||||
with their documented extra.
|
||||
|
||||
## Native openpi server
|
||||
|
||||
Install the small ComfyUI client dependencies:
|
||||
|
||||
```bash
|
||||
python -m pip install -r requirements-robotics-client.txt
|
||||
```
|
||||
|
||||
Run the official openpi policy WebSocket server in its own supported
|
||||
environment. The upstream runtime is currently tested on Ubuntu 22.04 and an
|
||||
NVIDIA GPU with more than 8 GB for inference; use WSL/Docker or a remote Linux
|
||||
server rather than forcing it into a macOS/Windows ComfyUI environment.
|
||||
|
||||
Use:
|
||||
|
||||
- `Flat keys (DROID / LIBERO)` for observations such as
|
||||
`observation/image`, `observation/wrist_image`, and `observation/state`;
|
||||
- `Nested images (ALOHA)` for `state`, an `images` mapping such as
|
||||
`cam_high`/wrist cameras, and `prompt`.
|
||||
|
||||
The workflow supplies key names, but the policy's own transform still defines
|
||||
the exact shapes and normalization. `OPENPI_API_KEY` is read only from the
|
||||
ComfyUI server environment. Remote endpoints require WSS and explicit
|
||||
`allow_remote=true`.
|
||||
|
||||
## Native Isaac-GR00T N1.7 server
|
||||
|
||||
Install the same lightweight robotics client requirements in ComfyUI. Run the
|
||||
official GR00T `PolicyServer` beside an embodiment-compatible `Gr00tPolicy`.
|
||||
The node sends the documented nested contract:
|
||||
|
||||
```text
|
||||
video.<camera> uint8 [batch=1, history, height, width, RGB=3]
|
||||
state.state float32[batch=1, history, state_dim]
|
||||
language.task string [batch=1, 1]
|
||||
```
|
||||
|
||||
The official server returns one or more physical-unit action streams with
|
||||
shape `[batch, horizon, dimension]`. The node flattens those streams while
|
||||
preserving their named slices. `GROOT_API_TOKEN` remains in the ComfyUI
|
||||
environment.
|
||||
|
||||
GR00T N1.7 currently targets NVIDIA CUDA/Jetson Linux and needs an
|
||||
embodiment-compatible base or post-trained checkpoint. A ComfyUI client on
|
||||
Windows, macOS, ROCm, or another machine may call that server over a trusted
|
||||
network, but remote access must be explicitly enabled. Native GR00T ZMQ does
|
||||
not encrypt traffic; use a private authenticated network/tunnel. Prefer the
|
||||
universal HTTPS bridge when transport-layer encryption is required.
|
||||
|
||||
## Model catalog: what “available” means
|
||||
|
||||
`VLA Model Catalog` distinguishes these states:
|
||||
|
||||
| Family | Example checkpoint | Route | Important qualification |
|
||||
| --- | --- | --- | --- |
|
||||
| SmolVLA | `lerobot/smolvla_base` | LeRobot HTTP sidecar | 450M and the best small starting point; fine-tune for the robot |
|
||||
| X-VLA | `lerobot/xvla-base` | LeRobot HTTP sidecar | 0.9B cross-embodiment base; use a matching domain checkpoint |
|
||||
| π0 | `lerobot/pi0_base` | LeRobot or openpi | Base/fine-tuning model, not a universal drop-in controller |
|
||||
| π0-FAST | `lerobot/pi0fast-base` | LeRobot or openpi | Faster tokenized action generation |
|
||||
| π0.5 | `lerobot/pi05_base` | LeRobot or openpi | Open-world generalization; still embodiment-specific |
|
||||
| GR00T N1.7 | `nvidia/GR00T-N1.7-3B` | GR00T ZMQ or LeRobot | Base has specific zero-shot tags; other robots need post-training |
|
||||
| X-Square WALL-OSS | `x-square-robot/wall-oss-flow` | LeRobot HTTP sidecar | MoE research model; validate checkpoint terms and embodiment |
|
||||
| MolmoAct2 | `lerobot/MolmoAct2-SO100_101-LeRobot` | LeRobot HTTP sidecar | Converted SO-100/SO-101 checkpoint |
|
||||
| VLA-JEPA | `lerobot/VLA-JEPA-Pretrain` | LeRobot HTTP sidecar | DROID pretrain plus LIBERO/SimplerEnv checkpoints |
|
||||
| LingBot-VA | `lerobot/lingbot_va_base` | LeRobot HTTP sidecar | Prefer its LIBERO-Long/RoboTwin post-train where applicable |
|
||||
| FastWAM | released LIBERO checkpoint | LeRobot HTTP sidecar | Heavy world-action research runtime |
|
||||
| EO-1 / EVO-1 | your trained checkpoint | LeRobot HTTP sidecar | Architecture support, not a universal ready-made controller |
|
||||
| OpenVLA-OFT | compatible OFT fine-tune | dedicated sidecar | OFT is the faster multi-image/high-frequency OpenVLA route |
|
||||
| Octo small | Octo small 27M | dedicated JAX sidecar | Lightweight legacy research baseline |
|
||||
|
||||
The catalog is a verified runtime/checkpoint map, not a promise that a base
|
||||
checkpoint understands an arbitrary robot. Exact data transforms and
|
||||
fine-tuning are part of the policy.
|
||||
|
||||
## Observation history and real-time use
|
||||
|
||||
Connect an `IMAGE` batch to a camera input to represent temporal history. All
|
||||
camera batches must have the same length, although a one-frame camera may
|
||||
broadcast. Use:
|
||||
|
||||
`Video Slice` → `VLM Adaptive Frame Sampler` or a live capture source →
|
||||
`VLM Image Pixel Budget` → `VLA Observation Builder`
|
||||
|
||||
For closed-loop robotics, do not run an unbounded ComfyUI queue for each motor
|
||||
tick. Use ComfyUI to prototype and inspect the observation/policy/safety
|
||||
contract, and use the policy runtime's asynchronous control support for the
|
||||
actual high-frequency loop. LeRobot supports asynchronous action chunks and
|
||||
GR00T supports TensorRT deployment; both are better places for timing-critical
|
||||
execution.
|
||||
|
||||
## Action safety semantics
|
||||
|
||||
The `VLA Action Safety Gate` checks:
|
||||
|
||||
- policy action dimension against the embodiment;
|
||||
- NaN and infinity;
|
||||
- minimum and maximum values;
|
||||
- maximum change per action dimension and control step;
|
||||
- the requested execution horizon.
|
||||
|
||||
Modes:
|
||||
|
||||
- `Block unsafe`: raise and stop the workflow on any violation.
|
||||
- `Clamp safely`: replace non-finite values conservatively, then clamp bounds
|
||||
and sequential per-step deltas.
|
||||
- `Hold position on unsafe`: replace the whole chunk with the explicitly
|
||||
supplied previous/current command.
|
||||
- `Report only`: preserve the raw trajectory and set
|
||||
`safe_for_handoff=false`.
|
||||
|
||||
For delta-action policies, `previous_action_json` means the previous delta
|
||||
command, not an absolute joint pose. Define the profile in the same units and
|
||||
semantics as the policy output.
|
||||
|
||||
`VLA Actions From JSON` imports recorded/simulator trajectories without a
|
||||
network policy. `VLA Action Chunk Replan` blends the unexecuted edge of an old
|
||||
chunk into a new chunk to reduce discontinuities, then the result should pass
|
||||
through the safety gate again. This deterministic blend is useful for workflow
|
||||
experiments but does not replace LeRobot's asynchronous controller or a
|
||||
policy-specific real-time chunking implementation.
|
||||
|
||||
## API example
|
||||
|
||||
`vla_http_policy_safety_api.json` is a ComfyUI API prompt graph. Put
|
||||
`robot_front.png` in `ComfyUI/input`, start a compatible sidecar, then POST:
|
||||
|
||||
```json
|
||||
{"prompt": {"...": "contents of vla_http_policy_safety_api.json"}}
|
||||
```
|
||||
|
||||
It builds an observation, calls the policy, clamps it against the explicit
|
||||
profile, renders the trajectory, and outputs both inference and safety JSON.
|
||||
|
||||
## Security checklist
|
||||
|
||||
- Keep all policy tokens in environment variables.
|
||||
- Leave `allow_remote=false` for local servers.
|
||||
- Remote universal endpoints must use HTTPS; remote openpi endpoints must use
|
||||
WSS.
|
||||
- Never expose GR00T ZMQ directly to an untrusted network.
|
||||
- Pin checkpoint revisions when reproducibility matters.
|
||||
- Treat camera images, task language, and robot state as sensitive data.
|
||||
- Do not connect action JSON directly to hardware without a separate
|
||||
supervised controller bridge and independent safety system.
|
||||
|
||||
Authoritative upstream documentation:
|
||||
|
||||
- [LeRobot installation](https://huggingface.co/docs/lerobot/main/en/installation)
|
||||
- [LeRobot SmolVLA](https://huggingface.co/docs/lerobot/smolvla)
|
||||
- [LeRobot asynchronous inference](https://huggingface.co/docs/lerobot/async)
|
||||
- [Physical Intelligence openpi](https://github.com/Physical-Intelligence/openpi)
|
||||
- [NVIDIA Isaac-GR00T](https://github.com/NVIDIA/Isaac-GR00T)
|
||||
- [OpenVLA and OFT](https://github.com/openvla/openvla)
|
||||
- [Octo](https://github.com/octo-models/octo)
|
||||
@@ -0,0 +1 @@
|
||||
"""Runnable, dependency-isolated robotics policy bridge examples."""
|
||||
@@ -0,0 +1,434 @@
|
||||
#!/usr/bin/env python
|
||||
"""Isolated LeRobot policy server for the ComfyUI VLA HTTP node.
|
||||
|
||||
Run this file in a dedicated environment that contains LeRobot and the
|
||||
policy-specific dependencies. Do not install LeRobot's full dependency stack
|
||||
into ComfyUI merely to use this bridge.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import argparse
|
||||
import base64
|
||||
import hmac
|
||||
import io
|
||||
import json
|
||||
import os
|
||||
import threading
|
||||
import time
|
||||
from http import HTTPStatus
|
||||
from http.server import BaseHTTPRequestHandler, ThreadingHTTPServer
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import Image
|
||||
|
||||
MAX_REQUEST_BYTES = 64 * 1024 * 1024
|
||||
MAX_CAMERAS = 16
|
||||
MAX_FRAMES_PER_CAMERA = 256
|
||||
MAX_IMAGE_BYTES = 8 * 1024 * 1024
|
||||
MAX_IMAGE_PIXELS = 16 * 1024 * 1024
|
||||
MAX_STATE_DIM = 2_048
|
||||
MAX_ACTION_DIM = 2_048
|
||||
MAX_TASK_CHARS = 16_384
|
||||
|
||||
|
||||
def _json_bytes(value: Any) -> bytes:
|
||||
return json.dumps(
|
||||
value,
|
||||
ensure_ascii=False,
|
||||
allow_nan=False,
|
||||
separators=(",", ":"),
|
||||
).encode("utf-8")
|
||||
|
||||
|
||||
def _device(value: str) -> str:
|
||||
if value != "auto":
|
||||
return value
|
||||
if torch.cuda.is_available():
|
||||
return "cuda"
|
||||
if hasattr(torch, "xpu") and torch.xpu.is_available():
|
||||
return "xpu"
|
||||
if hasattr(torch.backends, "mps") and torch.backends.mps.is_available():
|
||||
return "mps"
|
||||
return "cpu"
|
||||
|
||||
|
||||
def _decode_image(frame: dict[str, Any]) -> np.ndarray:
|
||||
if frame.get("encoding") != "base64-jpeg":
|
||||
raise ValueError("Only base64-jpeg camera frames are supported.")
|
||||
raw = base64.b64decode(frame["data"], validate=True)
|
||||
if len(raw) > MAX_IMAGE_BYTES:
|
||||
raise ValueError("Encoded camera frame exceeds the 8 MiB safety limit.")
|
||||
with Image.open(io.BytesIO(raw)) as image:
|
||||
if image.width * image.height > MAX_IMAGE_PIXELS:
|
||||
raise ValueError("Decoded camera frame exceeds the pixel safety limit.")
|
||||
return np.asarray(image.convert("RGB"), dtype=np.uint8).copy()
|
||||
|
||||
|
||||
def _decode_observation(payload: dict[str, Any]) -> dict[str, Any]:
|
||||
if payload.get("schema") != "comfyui-vlm/robot-observation":
|
||||
raise ValueError("Unsupported observation schema.")
|
||||
if int(payload.get("version", 0)) != 1:
|
||||
raise ValueError("Unsupported observation schema version.")
|
||||
cameras = payload.get("cameras")
|
||||
if not isinstance(cameras, dict) or not 1 <= len(cameras) <= MAX_CAMERAS:
|
||||
raise ValueError("cameras must contain between 1 and 16 entries.")
|
||||
observation: dict[str, Any] = {}
|
||||
for key, encoded_frames in cameras.items():
|
||||
key = str(key).strip()
|
||||
if not key or len(key) > 256 or any(ord(char) < 32 for char in key):
|
||||
raise ValueError("Camera names must contain 1 to 256 printable characters.")
|
||||
if not isinstance(encoded_frames, list) or not (
|
||||
1 <= len(encoded_frames) <= MAX_FRAMES_PER_CAMERA
|
||||
):
|
||||
raise ValueError(f"Camera {key!r} has an invalid history.")
|
||||
# Current LeRobot policy processors accept one current observation.
|
||||
# ComfyUI may send history for servers/models that use it; this generic
|
||||
# bridge deliberately selects the latest frame.
|
||||
array = _decode_image(encoded_frames[-1])
|
||||
tensor = torch.from_numpy(array).permute(2, 0, 1).to(torch.float32) / 255.0
|
||||
observation[key] = tensor.unsqueeze(0)
|
||||
state = np.asarray(payload.get("state"), dtype=np.float32)
|
||||
if (
|
||||
state.ndim != 1
|
||||
or not 1 <= state.size <= MAX_STATE_DIM
|
||||
or not np.isfinite(state).all()
|
||||
):
|
||||
raise ValueError(f"state must contain 1 to {MAX_STATE_DIM} finite values.")
|
||||
observation["observation.state"] = torch.from_numpy(state).unsqueeze(0)
|
||||
task = str(payload.get("task", "")).strip()
|
||||
if not task or len(task) > MAX_TASK_CHARS:
|
||||
raise ValueError(f"task must contain 1 to {MAX_TASK_CHARS} characters.")
|
||||
observation["task"] = task
|
||||
return observation
|
||||
|
||||
|
||||
def _postprocess_chunk(postprocessor, action: torch.Tensor) -> torch.Tensor:
|
||||
if action.ndim == 1:
|
||||
action = action.unsqueeze(0)
|
||||
if action.ndim == 2:
|
||||
# select_action normally returns [batch, dim].
|
||||
processed = postprocessor(action)
|
||||
if processed.ndim == 1:
|
||||
processed = processed.unsqueeze(0)
|
||||
return processed.unsqueeze(1) if processed.ndim == 2 else processed
|
||||
if action.ndim != 3:
|
||||
raise ValueError(f"Policy returned unsupported action shape {tuple(action.shape)}.")
|
||||
processed_steps = [postprocessor(action[:, index, :]) for index in range(action.shape[1])]
|
||||
return torch.stack(processed_steps, dim=1)
|
||||
|
||||
|
||||
def _feature_metadata(features: Any) -> dict[str, dict[str, Any]]:
|
||||
"""Return the portable part of a LeRobot policy feature contract."""
|
||||
|
||||
result: dict[str, dict[str, Any]] = {}
|
||||
for key, feature in (features or {}).items():
|
||||
if isinstance(feature, dict):
|
||||
feature_type = feature.get("type")
|
||||
shape = feature.get("shape", ())
|
||||
else:
|
||||
feature_type = getattr(feature, "type", None)
|
||||
shape = getattr(feature, "shape", ())
|
||||
feature_type = getattr(feature_type, "value", feature_type)
|
||||
dimensions: list[int | str | None] = []
|
||||
for dimension in shape or ():
|
||||
if dimension is None:
|
||||
dimensions.append(None)
|
||||
continue
|
||||
try:
|
||||
dimensions.append(int(dimension))
|
||||
except (TypeError, ValueError):
|
||||
dimensions.append(str(dimension))
|
||||
result[str(key)] = {
|
||||
"type": str(feature_type) if feature_type is not None else "UNKNOWN",
|
||||
"shape": dimensions,
|
||||
}
|
||||
return result
|
||||
|
||||
|
||||
def _optional_config_int(config: Any, name: str) -> int | None:
|
||||
value = getattr(config, name, None)
|
||||
try:
|
||||
return None if value is None else int(value)
|
||||
except (TypeError, ValueError):
|
||||
return None
|
||||
|
||||
|
||||
class PolicyRuntime:
|
||||
def __init__(
|
||||
self,
|
||||
*,
|
||||
policy_type: str,
|
||||
policy_path: str,
|
||||
revision: str | None,
|
||||
device: str,
|
||||
actions_per_chunk: int,
|
||||
idle_offload_seconds: float,
|
||||
):
|
||||
self.policy_type = policy_type
|
||||
self.policy_path = policy_path
|
||||
self.revision = revision
|
||||
self.device = _device(device)
|
||||
self.actions_per_chunk = actions_per_chunk
|
||||
self.idle_offload_seconds = idle_offload_seconds
|
||||
self.lock = threading.Lock()
|
||||
self.policy = None
|
||||
self.preprocessor = None
|
||||
self.postprocessor = None
|
||||
self.resident_device = "unloaded"
|
||||
self.last_request = 0.0
|
||||
self.load_seconds = 0.0
|
||||
self._load()
|
||||
if idle_offload_seconds > 0 and self.device != "cpu":
|
||||
threading.Thread(target=self._idle_worker, daemon=True).start()
|
||||
|
||||
def _load(self) -> None:
|
||||
from lerobot.policies import get_policy_class, make_pre_post_processors
|
||||
|
||||
started = time.perf_counter()
|
||||
policy_class = get_policy_class(self.policy_type)
|
||||
kwargs = {}
|
||||
if self.revision:
|
||||
kwargs["revision"] = self.revision
|
||||
self.policy = policy_class.from_pretrained(self.policy_path, **kwargs)
|
||||
self.policy.eval()
|
||||
self.policy.to(self.device)
|
||||
overrides = {"device": self.device}
|
||||
self.preprocessor, self.postprocessor = make_pre_post_processors(
|
||||
self.policy.config,
|
||||
pretrained_path=self.policy_path,
|
||||
pretrained_revision=self.revision,
|
||||
preprocessor_overrides={"device_processor": overrides},
|
||||
postprocessor_overrides={"device_processor": overrides},
|
||||
)
|
||||
self.resident_device = self.device
|
||||
self.last_request = time.monotonic()
|
||||
self.load_seconds = time.perf_counter() - started
|
||||
|
||||
def _ensure_resident(self) -> None:
|
||||
if self.resident_device != self.device:
|
||||
self.policy.to(self.device)
|
||||
self.resident_device = self.device
|
||||
|
||||
def _idle_worker(self) -> None:
|
||||
interval = min(max(self.idle_offload_seconds / 4, 1.0), 30.0)
|
||||
while True:
|
||||
time.sleep(interval)
|
||||
if time.monotonic() - self.last_request < self.idle_offload_seconds:
|
||||
continue
|
||||
if not self.lock.acquire(blocking=False):
|
||||
continue
|
||||
try:
|
||||
if (
|
||||
self.resident_device != "cpu"
|
||||
and time.monotonic() - self.last_request >= self.idle_offload_seconds
|
||||
):
|
||||
self.policy.to("cpu")
|
||||
self.resident_device = "cpu"
|
||||
finally:
|
||||
self.lock.release()
|
||||
|
||||
def metadata(self) -> dict[str, Any]:
|
||||
config = self.policy.config
|
||||
return {
|
||||
"protocol": "comfyui-vla-http-v1",
|
||||
"policy_type": self.policy_type,
|
||||
"policy_path": self.policy_path,
|
||||
"revision": self.revision,
|
||||
"configured_device": self.device,
|
||||
"resident_device": self.resident_device,
|
||||
"actions_per_chunk": self.actions_per_chunk,
|
||||
"idle_offload_seconds": self.idle_offload_seconds,
|
||||
"load_seconds": self.load_seconds,
|
||||
"policy_contract": {
|
||||
"input_features": _feature_metadata(
|
||||
getattr(config, "input_features", None)
|
||||
),
|
||||
"output_features": _feature_metadata(
|
||||
getattr(config, "output_features", None)
|
||||
),
|
||||
"observation_steps": _optional_config_int(config, "n_obs_steps"),
|
||||
"native_chunk_size": _optional_config_int(config, "chunk_size"),
|
||||
"native_action_steps": _optional_config_int(config, "n_action_steps"),
|
||||
},
|
||||
}
|
||||
|
||||
def infer(self, payload: dict[str, Any]) -> dict[str, Any]:
|
||||
observation = _decode_observation(payload)
|
||||
with self.lock:
|
||||
self._ensure_resident()
|
||||
started = time.perf_counter()
|
||||
processed = self.preprocessor(observation)
|
||||
preprocess_ms = (time.perf_counter() - started) * 1000
|
||||
started_inference = time.perf_counter()
|
||||
with torch.inference_mode():
|
||||
predictor = getattr(self.policy, "predict_action_chunk", None)
|
||||
if callable(predictor):
|
||||
action = predictor(processed)
|
||||
else:
|
||||
action = self.policy.select_action(processed)
|
||||
inference_ms = (time.perf_counter() - started_inference) * 1000
|
||||
started_postprocess = time.perf_counter()
|
||||
action = _postprocess_chunk(self.postprocessor, action)
|
||||
if action.ndim == 3:
|
||||
if action.shape[0] != 1:
|
||||
raise ValueError("Only policy batch size 1 is supported.")
|
||||
action = action[0]
|
||||
elif action.ndim == 1:
|
||||
action = action.unsqueeze(0)
|
||||
if action.ndim != 2:
|
||||
raise ValueError(f"Unexpected final action shape {tuple(action.shape)}.")
|
||||
action = action[: self.actions_per_chunk].detach().to("cpu", torch.float32)
|
||||
if not 1 <= int(action.shape[1]) <= MAX_ACTION_DIM:
|
||||
raise ValueError(
|
||||
f"Policy action dimension must be in [1, {MAX_ACTION_DIM}]."
|
||||
)
|
||||
if not torch.isfinite(action).all():
|
||||
# Preserve the response for ComfyUI's safety node, but do not
|
||||
# serialize non-standard JSON numbers.
|
||||
raise ValueError("Policy returned NaN or infinite action values.")
|
||||
postprocess_ms = (time.perf_counter() - started_postprocess) * 1000
|
||||
self.last_request = time.monotonic()
|
||||
return {
|
||||
"actions": action.tolist(),
|
||||
"server_timing": {
|
||||
"preprocess_ms": preprocess_ms,
|
||||
"infer_ms": inference_ms,
|
||||
"postprocess_ms": postprocess_ms,
|
||||
},
|
||||
"policy": {
|
||||
"type": self.policy_type,
|
||||
"path": self.policy_path,
|
||||
"device": self.device,
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
class PolicyHandler(BaseHTTPRequestHandler):
|
||||
server_version = "ComfyUI-VLA-Policy/1"
|
||||
|
||||
def log_message(self, format_string: str, *args: Any) -> None:
|
||||
# The request path is safe to log. Headers and bodies may contain
|
||||
# credentials or camera/state data and are intentionally excluded.
|
||||
print(f"{self.address_string()} - {format_string % args}")
|
||||
|
||||
@property
|
||||
def runtime(self) -> PolicyRuntime:
|
||||
return self.server.runtime
|
||||
|
||||
@property
|
||||
def token(self) -> str:
|
||||
return self.server.token
|
||||
|
||||
def _authorized(self) -> bool:
|
||||
if not self.token:
|
||||
return True
|
||||
supplied = self.headers.get("Authorization", "")
|
||||
expected = f"Bearer {self.token}"
|
||||
return hmac.compare_digest(supplied, expected)
|
||||
|
||||
def _send(self, status: HTTPStatus, value: Any) -> None:
|
||||
body = _json_bytes(value)
|
||||
self.send_response(status.value)
|
||||
self.send_header("Content-Type", "application/json; charset=utf-8")
|
||||
self.send_header("Content-Length", str(len(body)))
|
||||
self.send_header("Cache-Control", "no-store")
|
||||
self.send_header("X-Content-Type-Options", "nosniff")
|
||||
self.end_headers()
|
||||
self.wfile.write(body)
|
||||
|
||||
def do_GET(self) -> None: # noqa: N802
|
||||
if self.path not in {"/healthz", "/v1/metadata"}:
|
||||
self._send(HTTPStatus.NOT_FOUND, {"error": "not_found"})
|
||||
return
|
||||
if not self._authorized():
|
||||
self._send(HTTPStatus.UNAUTHORIZED, {"error": "unauthorized"})
|
||||
return
|
||||
if self.path == "/healthz":
|
||||
self._send(HTTPStatus.OK, {"status": "ok"})
|
||||
else:
|
||||
self._send(HTTPStatus.OK, self.runtime.metadata())
|
||||
|
||||
def do_POST(self) -> None: # noqa: N802
|
||||
if self.path != "/v1/infer":
|
||||
self._send(HTTPStatus.NOT_FOUND, {"error": "not_found"})
|
||||
return
|
||||
if not self._authorized():
|
||||
self._send(HTTPStatus.UNAUTHORIZED, {"error": "unauthorized"})
|
||||
return
|
||||
try:
|
||||
content_length = int(self.headers.get("Content-Length", "0"))
|
||||
if not 1 <= content_length <= MAX_REQUEST_BYTES:
|
||||
raise ValueError("Request body size is invalid.")
|
||||
body = self.rfile.read(content_length)
|
||||
payload = json.loads(body)
|
||||
if not isinstance(payload, dict):
|
||||
raise ValueError("Request body must be a JSON object.")
|
||||
result = self.runtime.infer(payload)
|
||||
except (TypeError, ValueError, json.JSONDecodeError) as exc:
|
||||
self._send(HTTPStatus.BAD_REQUEST, {"error": str(exc)[:1000]})
|
||||
return
|
||||
except Exception as exc:
|
||||
# Do not return tracebacks, request data, environment variables, or
|
||||
# authorization headers across the network.
|
||||
self._send(
|
||||
HTTPStatus.INTERNAL_SERVER_ERROR,
|
||||
{"error": f"{type(exc).__name__}: {str(exc)[:800]}"},
|
||||
)
|
||||
return
|
||||
self._send(HTTPStatus.OK, result)
|
||||
|
||||
|
||||
def main() -> None:
|
||||
parser = argparse.ArgumentParser(
|
||||
description="Serve one LeRobot policy through the ComfyUI VLA HTTP protocol."
|
||||
)
|
||||
parser.add_argument("--policy-type", required=True, help="LeRobot policy type, e.g. smolvla")
|
||||
parser.add_argument("--policy-path", required=True, help="Hub repo id or local checkpoint")
|
||||
parser.add_argument("--revision", default=None, help="Optional immutable Hub revision")
|
||||
parser.add_argument("--device", default="auto", help="auto, cuda, mps, xpu, or cpu")
|
||||
parser.add_argument("--host", default="127.0.0.1")
|
||||
parser.add_argument("--port", type=int, default=8787)
|
||||
parser.add_argument("--actions-per-chunk", type=int, default=16)
|
||||
parser.add_argument(
|
||||
"--idle-offload-seconds",
|
||||
type=float,
|
||||
default=0.0,
|
||||
help="Move the policy to CPU after this idle period; 0 keeps it resident.",
|
||||
)
|
||||
args = parser.parse_args()
|
||||
if not 1 <= args.port <= 65_535:
|
||||
parser.error("--port must be in [1, 65535]")
|
||||
if not 1 <= args.actions_per_chunk <= 4096:
|
||||
parser.error("--actions-per-chunk must be in [1, 4096]")
|
||||
if args.idle_offload_seconds < 0:
|
||||
parser.error("--idle-offload-seconds must be non-negative")
|
||||
|
||||
runtime = PolicyRuntime(
|
||||
policy_type=args.policy_type,
|
||||
policy_path=args.policy_path,
|
||||
revision=args.revision,
|
||||
device=args.device,
|
||||
actions_per_chunk=args.actions_per_chunk,
|
||||
idle_offload_seconds=args.idle_offload_seconds,
|
||||
)
|
||||
token = os.environ.get("VLA_POLICY_TOKEN", "").strip()
|
||||
server = ThreadingHTTPServer((args.host, args.port), PolicyHandler)
|
||||
server.runtime = runtime
|
||||
server.token = token
|
||||
print(
|
||||
f"Policy ready at http://{args.host}:{args.port}/v1/infer "
|
||||
f"(type={args.policy_type}, device={runtime.device}, auth={'on' if token else 'off'})"
|
||||
)
|
||||
try:
|
||||
server.serve_forever()
|
||||
except KeyboardInterrupt:
|
||||
pass
|
||||
finally:
|
||||
server.server_close()
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -0,0 +1,130 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadImage",
|
||||
"inputs": {
|
||||
"image": "robot_front.png"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "VLAEmbodimentProfile",
|
||||
"inputs": {
|
||||
"preset": "Generic 7-DoF joint + gripper",
|
||||
"control_hz": 20.0,
|
||||
"state_names_json": "",
|
||||
"action_names_json": "",
|
||||
"action_min_json": "",
|
||||
"action_max_json": "",
|
||||
"max_delta_json": "",
|
||||
"camera_names_json": "",
|
||||
"action_mode_override": ""
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "VLAObservationBuilder",
|
||||
"inputs": {
|
||||
"task": "Pick up the blue cube and place it in the tray.",
|
||||
"state_json": "[0, 0, 0, 0, 0, 0, 0, 0]",
|
||||
"primary_image": [
|
||||
"1",
|
||||
0
|
||||
],
|
||||
"primary_camera": "observation.images.front",
|
||||
"history_fps": 10.0,
|
||||
"timestamp": 0.0,
|
||||
"embodiment": [
|
||||
"2",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "VLAHTTPPolicy",
|
||||
"inputs": {
|
||||
"observation": [
|
||||
"3",
|
||||
0
|
||||
],
|
||||
"endpoint": "http://127.0.0.1:8787",
|
||||
"timeout_seconds": 120.0,
|
||||
"include_history": true,
|
||||
"allow_remote": false
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "VLAActionSafety",
|
||||
"inputs": {
|
||||
"actions": [
|
||||
"4",
|
||||
0
|
||||
],
|
||||
"embodiment": [
|
||||
"2",
|
||||
0
|
||||
],
|
||||
"mode": "Clamp safely",
|
||||
"execution_horizon": 8,
|
||||
"previous_action_json": "[0, 0, 0, 0, 0, 0, 0, 0]"
|
||||
}
|
||||
},
|
||||
"6": {
|
||||
"class_type": "VLATrajectoryPreview",
|
||||
"inputs": {
|
||||
"actions": [
|
||||
"5",
|
||||
0
|
||||
],
|
||||
"width": 960,
|
||||
"height": 480,
|
||||
"embodiment": [
|
||||
"2",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"7": {
|
||||
"class_type": "VLAActionInspect",
|
||||
"inputs": {
|
||||
"actions": [
|
||||
"5",
|
||||
0
|
||||
],
|
||||
"step_index": 0
|
||||
}
|
||||
},
|
||||
"8": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"6",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"9": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"4",
|
||||
1
|
||||
]
|
||||
}
|
||||
},
|
||||
"10": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"5",
|
||||
1
|
||||
]
|
||||
}
|
||||
},
|
||||
"11": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"7",
|
||||
0
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,57 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "SimpleText",
|
||||
"inputs": {
|
||||
"input_text": "Model response:\n```json\n{\"scene\":{\"subject\":\"warehouse robot\",\"action\":\"moving a blue crate\"}}\n```"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "VLMJSONExtract",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"1",
|
||||
0
|
||||
],
|
||||
"path": "$.scene.action",
|
||||
"output_format": "Text",
|
||||
"if_missing": "Error",
|
||||
"default_value": ""
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "VLMTextTemplate",
|
||||
"inputs": {
|
||||
"template": "{instruction}\n\nObserved action: {text1}",
|
||||
"variables_json": "{\"instruction\":\"Write one concise video-generation prompt.\"}",
|
||||
"missing_values": "Error",
|
||||
"text1": [
|
||||
"2",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "VLMTextClean",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"3",
|
||||
0
|
||||
],
|
||||
"unicode_normalization": "NFC",
|
||||
"whitespace": "Normalize line endings",
|
||||
"trim_edges": true,
|
||||
"remove_outer_markdown_fence": false,
|
||||
"deduplicate_lines": false,
|
||||
"max_characters": 0
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"4",
|
||||
0
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,124 @@
|
||||
# Vision API examples
|
||||
|
||||
These files contain ComfyUI API prompt graphs: the object that belongs under
|
||||
the `prompt` key in a `POST /prompt` request. They are not frontend workflow
|
||||
exports and are not intended for drag-and-drop import into the canvas.
|
||||
|
||||
Before queueing:
|
||||
|
||||
1. Copy the named image/video into `ComfyUI/input`, or change the `image`/`file`
|
||||
widget value to an existing input filename.
|
||||
2. Restart ComfyUI after installing or updating this node pack.
|
||||
3. Confirm every `class_type` is present in `/object_info`.
|
||||
4. Wrap the loaded JSON as `{"prompt": graph}` in the API request.
|
||||
|
||||
## Examples
|
||||
|
||||
### `grounding_dino_image_api.json`
|
||||
|
||||
Runs Grounding DINO Tiny over `grounding_input.png`. Node 2 outputs:
|
||||
|
||||
| Index | Output |
|
||||
| ---: | --- |
|
||||
| 0 | `VLM_DETECTIONS` |
|
||||
| 1 | Structured detection JSON |
|
||||
| 2 | Detection overlay |
|
||||
| 3 | Box mask |
|
||||
| 4 | Core nested per-frame `BOUNDING_BOX` |
|
||||
| 5 | Flat metadata-rich `BOUNDING_BOXES` |
|
||||
|
||||
`PreviewImage` displays output 2 and `ViewText` reports output 1.
|
||||
|
||||
### `vlm_performance_preflight_api.json`
|
||||
|
||||
Loads `vlm_api_people_birds.mp4` with Comfy core video nodes, applies the
|
||||
`Fast video` performance profile, runs the track-aware adaptive sampler, and
|
||||
then applies a 14-pixel-aligned image budget. The preview shows the exact batch
|
||||
that can be connected to any local or hosted VLM. Three `ViewText` nodes report
|
||||
the selected source indices/timestamps, pixel reduction, and active profile.
|
||||
|
||||
### `moondream3_preview_svg_segment_api.json`
|
||||
|
||||
Runs the official Moondream 3 Preview SVG segmentation skill over
|
||||
`moondream_segment_input.png`. Read the linked model license and change
|
||||
`license_accepted` to `true` before queueing. The graph previews the
|
||||
black/white mask, isolated foreground cutout, and mask/box/polygon overlay;
|
||||
`ViewText` receives the exact native SVG path plus its normalized bbox.
|
||||
|
||||
Moondream's path coordinates are normalized within the returned bbox. The
|
||||
node preserves that path verbatim, safely flattens curves/arcs, applies an
|
||||
even-odd fill for subpath holes, and supersamples the raster edge. The
|
||||
canonical detection keeps both the primary polygon and the full in-process
|
||||
mask.
|
||||
|
||||
### `moondream31_video_detect_api.json`
|
||||
|
||||
Loads `moondream_video_input.mp4`, passes the real frame batch and source FPS
|
||||
to Moondream, and analyzes every frame with four concurrent requests. Photon
|
||||
uses the Loader's `max_batch_size=4` scheduler capacity to form dynamic
|
||||
batches. `ViewText` reports measured throughput and real-time factor. Increase
|
||||
`frame_stride` to 2, 3, or more when full-frame analysis cannot keep up with
|
||||
the source FPS; the canonical results preserve original frame indices and
|
||||
timestamps.
|
||||
|
||||
### `sam2_video_tracking_api.json`
|
||||
|
||||
Runs this bounded pipeline:
|
||||
|
||||
`LoadVideo` → `Video Slice` → `GetVideoComponents` → `ImageScale` →
|
||||
`ImageFromBatch` → Grounding DINO first-frame detection → SAM2.1 propagation.
|
||||
|
||||
The example limits the source to two seconds, scales its largest dimension to
|
||||
768 pixels while preserving aspect ratio, unloads Grounding DINO after
|
||||
seeding, and keeps SAM2.1 video state on CPU. The example requests only the
|
||||
union mask volume; change `mask_output` to `union_and_objects` only when every
|
||||
per-object mask is required. `VLMTrackReport` is an output node and the final
|
||||
`PreviewImage` displays SAM2.1 output index 4.
|
||||
|
||||
For a longer source, change `start_time` and keep a bounded `duration`.
|
||||
Independent slices create independent object-ID sessions.
|
||||
|
||||
### `sam3_core_adapter_blueprint_api.json`
|
||||
|
||||
Uses ComfyUI core nodes to load and run SAM3.1, then passes core
|
||||
`SAM3_TRACK_DATA` through `VLMSAM3TrackAdapter`. The adapter's output 1 is the
|
||||
unchanged core payload consumed by `SAM3_TrackPreview`; output 0 is canonical
|
||||
`VLM_TRACKS` consumed by `VLMTrackReport`.
|
||||
|
||||
The graph intentionally names:
|
||||
|
||||
`ComfyUI/models/checkpoints/sam3.1_multiplex_fp16.safetensors`
|
||||
|
||||
The checkpoint is not bundled. Review the SAM License before downloading
|
||||
[Comfy-Org/sam3.1](https://huggingface.co/Comfy-Org/sam3.1). ComfyUI rejects
|
||||
the graph at prompt validation when the named checkpoint is absent. Use the
|
||||
SAM2.1 example when SAM3.1 access or compatible core support is unavailable.
|
||||
|
||||
## Output history
|
||||
|
||||
ComfyUI returns image/video previews in the execution history and text reports
|
||||
in the output-node UI payload. Canonical JSON is also available on the linked
|
||||
string outputs. Dense masks intentionally stay as tensors rather than being
|
||||
embedded in the JSON report.
|
||||
|
||||
## Creator mask outputs
|
||||
|
||||
`VLM Detections to Masks` preserves its original first three outputs and
|
||||
appends creator-ready derivatives:
|
||||
|
||||
| Index | Output |
|
||||
| ---: | --- |
|
||||
| 0 | Per-frame combined/union `MASK` |
|
||||
| 1 | Flattened per-object `MASK` batch |
|
||||
| 2 | JSON mapping each object mask to its frame/detection/track |
|
||||
| 3 | Per-frame inverse/background `MASK` |
|
||||
| 4 | Combined masks as black-and-white `IMAGE` batches |
|
||||
| 5 | Individual masks as black-and-white `IMAGE` batches |
|
||||
| 6 | Stable-color per-frame instance maps |
|
||||
|
||||
All binary mask values are exactly zero or one. `VLM Mask Processor` can grow,
|
||||
shrink, and feather any of these masks and returns processed, binary, inverse,
|
||||
and black-and-white image outputs. `VLM Mask Composite` accepts the resulting
|
||||
mask plus still-image or video frames and returns a composite, isolated
|
||||
foreground, background-only plate, and mask image. Connect an optional
|
||||
background image/video batch to replace the solid background color.
|
||||
@@ -0,0 +1,45 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadImage",
|
||||
"inputs": {
|
||||
"image": "grounding_input.png"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "VLMOpenVocabularyDetection",
|
||||
"inputs": {
|
||||
"image": [
|
||||
"1",
|
||||
0
|
||||
],
|
||||
"model": "Grounding DINO Tiny (fast)",
|
||||
"labels": "person, dog, bicycle",
|
||||
"box_threshold": 0.3,
|
||||
"text_threshold": 0.25,
|
||||
"max_detections": 100,
|
||||
"fps": 1.0,
|
||||
"nms_threshold": 0.5,
|
||||
"precision": "auto",
|
||||
"batch_size": 1,
|
||||
"unload_after": false
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"2",
|
||||
2
|
||||
]
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"2",
|
||||
1
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,76 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadVideo",
|
||||
"inputs": {
|
||||
"file": "moondream_video_input.mp4"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "GetVideoComponents",
|
||||
"inputs": {
|
||||
"video": [
|
||||
"1",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "Moondream31Loader",
|
||||
"inputs": {
|
||||
"license_accepted": false,
|
||||
"device": "Auto",
|
||||
"max_batch_size": 4,
|
||||
"kv_cache_profile": "Balanced (8K pages)",
|
||||
"model_or_adapter": "moondream3.1-9B-A2B"
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "Moondream31Detect",
|
||||
"inputs": {
|
||||
"model": [
|
||||
"3",
|
||||
0
|
||||
],
|
||||
"image": [
|
||||
"2",
|
||||
0
|
||||
],
|
||||
"object": "person",
|
||||
"fps": [
|
||||
"2",
|
||||
2
|
||||
],
|
||||
"frame_stride": 1,
|
||||
"parallel_requests": 4,
|
||||
"max_objects": 100,
|
||||
"unload_after": false
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"4",
|
||||
2
|
||||
]
|
||||
}
|
||||
},
|
||||
"6": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"4",
|
||||
6
|
||||
]
|
||||
}
|
||||
},
|
||||
"7": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"4",
|
||||
1
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,74 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadImage",
|
||||
"inputs": {
|
||||
"image": "moondream_segment_input.png"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "Moondream31Loader",
|
||||
"inputs": {
|
||||
"license_accepted": false,
|
||||
"device": "Auto",
|
||||
"max_batch_size": 4,
|
||||
"kv_cache_profile": "Balanced (8K pages)",
|
||||
"model_or_adapter": "moondream3-preview"
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "Moondream31Segment",
|
||||
"inputs": {
|
||||
"model": [
|
||||
"2",
|
||||
0
|
||||
],
|
||||
"image": [
|
||||
"1",
|
||||
0
|
||||
],
|
||||
"object": "main foreground object",
|
||||
"fps": 1.0,
|
||||
"frame_stride": 1,
|
||||
"parallel_requests": 1,
|
||||
"svg_supersample": 4,
|
||||
"unload_after": false,
|
||||
"spatial_refs_json": "[]"
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"3",
|
||||
4
|
||||
]
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"3",
|
||||
5
|
||||
]
|
||||
}
|
||||
},
|
||||
"6": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"3",
|
||||
6
|
||||
]
|
||||
}
|
||||
},
|
||||
"7": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"3",
|
||||
2
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,116 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadVideo",
|
||||
"inputs": {
|
||||
"file": "tracking_input.mp4"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "Video Slice",
|
||||
"inputs": {
|
||||
"video": [
|
||||
"1",
|
||||
0
|
||||
],
|
||||
"start_time": 0.0,
|
||||
"duration": 2.0,
|
||||
"strict_duration": false
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "GetVideoComponents",
|
||||
"inputs": {
|
||||
"video": [
|
||||
"2",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "ImageScaleToMaxDimension",
|
||||
"inputs": {
|
||||
"image": [
|
||||
"3",
|
||||
0
|
||||
],
|
||||
"upscale_method": "area",
|
||||
"largest_size": 768
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "ImageFromBatch",
|
||||
"inputs": {
|
||||
"image": [
|
||||
"4",
|
||||
0
|
||||
],
|
||||
"batch_index": 0,
|
||||
"length": 1
|
||||
}
|
||||
},
|
||||
"6": {
|
||||
"class_type": "VLMOpenVocabularyDetection",
|
||||
"inputs": {
|
||||
"image": [
|
||||
"5",
|
||||
0
|
||||
],
|
||||
"model": "Grounding DINO Tiny (fast)",
|
||||
"labels": "person, dog, vehicle",
|
||||
"box_threshold": 0.3,
|
||||
"text_threshold": 0.25,
|
||||
"max_detections": 16,
|
||||
"fps": [
|
||||
"3",
|
||||
2
|
||||
],
|
||||
"nms_threshold": 0.5,
|
||||
"precision": "auto",
|
||||
"batch_size": 1,
|
||||
"unload_after": true
|
||||
}
|
||||
},
|
||||
"7": {
|
||||
"class_type": "VLMSAM2VideoSegmentation",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"4",
|
||||
0
|
||||
],
|
||||
"model": "SAM2.1 Hiera Tiny (fast)",
|
||||
"seed_frame": 0,
|
||||
"fps": [
|
||||
"3",
|
||||
2
|
||||
],
|
||||
"detections": [
|
||||
"6",
|
||||
0
|
||||
],
|
||||
"mask_threshold": 0.0,
|
||||
"precision": "auto",
|
||||
"keep_video_on_cpu": true,
|
||||
"mask_output": "union_only",
|
||||
"render_preview": true,
|
||||
"unload_after": false
|
||||
}
|
||||
},
|
||||
"8": {
|
||||
"class_type": "VLMTrackReport",
|
||||
"inputs": {
|
||||
"tracks": [
|
||||
"7",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"9": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"7",
|
||||
4
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,116 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadVideo",
|
||||
"inputs": {
|
||||
"file": "tracking_input.mp4"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "Video Slice",
|
||||
"inputs": {
|
||||
"video": [
|
||||
"1",
|
||||
0
|
||||
],
|
||||
"start_time": 0.0,
|
||||
"duration": 2.0,
|
||||
"strict_duration": false
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "GetVideoComponents",
|
||||
"inputs": {
|
||||
"video": [
|
||||
"2",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "ImageScaleToMaxDimension",
|
||||
"inputs": {
|
||||
"image": [
|
||||
"3",
|
||||
0
|
||||
],
|
||||
"upscale_method": "area",
|
||||
"largest_size": 768
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "CheckpointLoaderSimple",
|
||||
"inputs": {
|
||||
"ckpt_name": "sam3.1_multiplex_fp16.safetensors"
|
||||
}
|
||||
},
|
||||
"6": {
|
||||
"class_type": "CLIPTextEncode",
|
||||
"inputs": {
|
||||
"text": "person, dog, vehicle",
|
||||
"clip": [
|
||||
"5",
|
||||
1
|
||||
]
|
||||
}
|
||||
},
|
||||
"7": {
|
||||
"class_type": "SAM3_VideoTrack",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"4",
|
||||
0
|
||||
],
|
||||
"model": [
|
||||
"5",
|
||||
0
|
||||
],
|
||||
"conditioning": [
|
||||
"6",
|
||||
0
|
||||
],
|
||||
"detection_threshold": 0.5,
|
||||
"max_objects": 8,
|
||||
"detect_interval": 1
|
||||
}
|
||||
},
|
||||
"8": {
|
||||
"class_type": "VLMSAM3TrackAdapter",
|
||||
"inputs": {
|
||||
"track_data": [
|
||||
"7",
|
||||
0
|
||||
],
|
||||
"fps": [
|
||||
"3",
|
||||
2
|
||||
]
|
||||
}
|
||||
},
|
||||
"9": {
|
||||
"class_type": "VLMTrackReport",
|
||||
"inputs": {
|
||||
"tracks": [
|
||||
"8",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"10": {
|
||||
"class_type": "SAM3_TrackPreview",
|
||||
"inputs": {
|
||||
"track_data": [
|
||||
"8",
|
||||
1
|
||||
],
|
||||
"images": [
|
||||
"4",
|
||||
0
|
||||
],
|
||||
"opacity": 0.5,
|
||||
"fps": [
|
||||
"3",
|
||||
2
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,91 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadVideo",
|
||||
"inputs": {
|
||||
"file": "video_understanding_input.mp4"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "GetVideoComponents",
|
||||
"inputs": {
|
||||
"video": [
|
||||
"1",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "VLMVideoTemporalReasoner",
|
||||
"inputs": {
|
||||
"frames": [
|
||||
"2",
|
||||
0
|
||||
],
|
||||
"fps": [
|
||||
"2",
|
||||
2
|
||||
],
|
||||
"task": "Detailed temporal summary",
|
||||
"question": "Describe what happens over time and identify the visible evidence.",
|
||||
"model": "Qwen 3 VL 2B Instruct",
|
||||
"custom_model_id": "",
|
||||
"memory_mode": "ComfyUI managed (BF16)",
|
||||
"max_frames": 16,
|
||||
"max_events": 24,
|
||||
"max_new_tokens": 768,
|
||||
"strategy": "Hybrid: scene + motion + tracks",
|
||||
"minimum_gap_seconds": 0.15,
|
||||
"analysis_max_side": 448,
|
||||
"attention_mode": "Auto (SDPA)",
|
||||
"enable_thinking": false,
|
||||
"strict_output": true,
|
||||
"unload_after": false,
|
||||
"stream_output": true
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"3",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"3",
|
||||
6
|
||||
]
|
||||
}
|
||||
},
|
||||
"6": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"3",
|
||||
7
|
||||
]
|
||||
}
|
||||
},
|
||||
"7": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"3",
|
||||
5
|
||||
]
|
||||
}
|
||||
},
|
||||
"8": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"3",
|
||||
3
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,98 @@
|
||||
{
|
||||
"1": {
|
||||
"class_type": "LoadVideo",
|
||||
"inputs": {
|
||||
"file": "vlm_api_people_birds.mp4"
|
||||
}
|
||||
},
|
||||
"2": {
|
||||
"class_type": "GetVideoComponents",
|
||||
"inputs": {
|
||||
"video": [
|
||||
"1",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"3": {
|
||||
"class_type": "VLMPerformanceProfile",
|
||||
"inputs": {
|
||||
"profile": "Fast video"
|
||||
}
|
||||
},
|
||||
"4": {
|
||||
"class_type": "VLMAdaptiveFrameSampler",
|
||||
"inputs": {
|
||||
"frames": [
|
||||
"2",
|
||||
0
|
||||
],
|
||||
"fps": [
|
||||
"2",
|
||||
2
|
||||
],
|
||||
"max_frames": [
|
||||
"3",
|
||||
0
|
||||
],
|
||||
"strategy": "Hybrid: scene + motion + tracks",
|
||||
"minimum_gap_seconds": 0.15,
|
||||
"thumbnail_size": 96
|
||||
}
|
||||
},
|
||||
"5": {
|
||||
"class_type": "VLMImagePixelBudget",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"4",
|
||||
0
|
||||
],
|
||||
"max_megapixels": [
|
||||
"3",
|
||||
1
|
||||
],
|
||||
"max_edge": [
|
||||
"3",
|
||||
2
|
||||
],
|
||||
"multiple": "14",
|
||||
"resize_quality": "Fast (area)"
|
||||
}
|
||||
},
|
||||
"6": {
|
||||
"class_type": "PreviewImage",
|
||||
"inputs": {
|
||||
"images": [
|
||||
"5",
|
||||
0
|
||||
]
|
||||
}
|
||||
},
|
||||
"7": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"4",
|
||||
3
|
||||
]
|
||||
}
|
||||
},
|
||||
"8": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"5",
|
||||
3
|
||||
]
|
||||
}
|
||||
},
|
||||
"9": {
|
||||
"class_type": "ViewText",
|
||||
"inputs": {
|
||||
"text": [
|
||||
"3",
|
||||
5
|
||||
]
|
||||
}
|
||||
}
|
||||
}
|
||||
-314
@@ -1,314 +0,0 @@
|
||||
import os
|
||||
import json
|
||||
import shutil
|
||||
from os.path import join, dirname, abspath, exists
|
||||
from os import makedirs, symlink, readlink
|
||||
import platform
|
||||
import subprocess
|
||||
import sys
|
||||
import importlib.util
|
||||
import re
|
||||
import torch
|
||||
import cpuinfo
|
||||
import packaging.tags
|
||||
from requests import get
|
||||
import asyncio
|
||||
import inspect
|
||||
import aiohttp
|
||||
from server import PromptServer
|
||||
from tqdm import tqdm
|
||||
import pkg_resources
|
||||
|
||||
|
||||
|
||||
def get_python_version():
|
||||
"""Return the Python version in a concise format, e.g., '39' for Python 3.9."""
|
||||
version_match = re.match(r"3\.(\d+)", platform.python_version())
|
||||
if version_match:
|
||||
return "3" + version_match.group(1)
|
||||
else:
|
||||
return None
|
||||
|
||||
def get_system_info():
|
||||
"""Gather system information related to NVIDIA GPU, CUDA version, AVX2 support, Python version, OS, and platform tag."""
|
||||
system_info = {
|
||||
'gpu': False,
|
||||
'cuda_version': None,
|
||||
'avx2': False,
|
||||
'python_version': get_python_version(),
|
||||
'os': platform.system(),
|
||||
'os_bit': platform.architecture()[0].replace("bit", ""),
|
||||
'platform_tag': None,
|
||||
}
|
||||
|
||||
# Check for NVIDIA GPU and CUDA version
|
||||
if importlib.util.find_spec('torch'):
|
||||
system_info['gpu'] = torch.cuda.is_available()
|
||||
if system_info['gpu']:
|
||||
system_info['cuda_version'] = "cu" + torch.version.cuda.replace(".", "").strip()
|
||||
|
||||
# Check for AVX2 support
|
||||
if importlib.util.find_spec('cpuinfo'):
|
||||
system_info['avx2'] = 'avx2' in cpuinfo.get_cpu_info()['flags']
|
||||
|
||||
# Determine the platform tag
|
||||
if importlib.util.find_spec('packaging.tags'):
|
||||
system_info['platform_tag'] = next(packaging.tags.sys_tags()).platform
|
||||
|
||||
return system_info
|
||||
|
||||
def latest_lamacpp():
|
||||
try:
|
||||
response = get("https://api.github.com/repos/abetlen/llama-cpp-python/releases/latest")
|
||||
return response.json()["tag_name"].replace("v", "")
|
||||
except Exception:
|
||||
return "0.2.20"
|
||||
|
||||
def install_package(package_name, custom_command=None):
|
||||
if not package_is_installed(package_name):
|
||||
print(f"Installing {package_name}...")
|
||||
command = [sys.executable, "-m", "pip", "install", package_name, "--no-cache-dir"]
|
||||
if custom_command:
|
||||
command += custom_command.split()
|
||||
subprocess.check_call(command)
|
||||
else:
|
||||
print(f"{package_name} is already installed.")
|
||||
|
||||
def package_is_installed(package_name):
|
||||
return importlib.util.find_spec(package_name) is not None
|
||||
|
||||
def install_llama(system_info):
|
||||
imported = package_is_installed("llama-cpp-python") or package_is_installed("llama_cpp")
|
||||
if imported:
|
||||
print("llama-cpp installed")
|
||||
else:
|
||||
lcpp_version = latest_lamacpp()
|
||||
base_url = "https://github.com/abetlen/llama-cpp-python/releases/download/v"
|
||||
avx = "AVX2" if system_info['avx2'] else "AVX"
|
||||
if system_info['gpu']:
|
||||
cuda_version = system_info['cuda_version']
|
||||
custom_command = f"--force-reinstall --no-deps --index-url=https://jllllll.github.io/llama-cpp-python-cuBLAS-wheels/{avx}/{cuda_version}"
|
||||
else:
|
||||
custom_command = f"{base_url}{lcpp_version}/llama_cpp_python-{lcpp_version}-{system_info['platform_tag']}.whl"
|
||||
install_package("llama-cpp-python", custom_command=custom_command)
|
||||
|
||||
def install_autogptq(system_info):
|
||||
# Check OS compatibility
|
||||
imported = package_is_installed("auto_gptq")
|
||||
if imported:
|
||||
print("AutoGPTQ installed")
|
||||
else:
|
||||
if system_info['os'] not in ['Linux', 'Windows']:
|
||||
print("AutoGPTQ is not supported on your operating system.")
|
||||
return
|
||||
|
||||
# Prepare base install command
|
||||
base_command = [sys.executable, "-m", "pip", "install", "auto-gptq"]
|
||||
|
||||
# Determine the specific install command based on GPU and CUDA/ROCm version
|
||||
if system_info['gpu']:
|
||||
if 'cuda_version' in system_info and system_info['cuda_version'] in ['cu118', 'cu121']:
|
||||
if system_info['cuda_version'] == 'cu118':
|
||||
base_command += ["--extra-index-url", "https://huggingface.github.io/autogptq-index/whl/cu118/"]
|
||||
# No extra URL needed for cu121 as it's the default
|
||||
elif 'rocm_version' in system_info and system_info['rocm_version'] == 'rocm573':
|
||||
base_command += ["--extra-index-url", "https://huggingface.github.io/autogptq-index/whl/rocm573/"]
|
||||
else:
|
||||
print("Unsupported GPU configuration for AutoGPTQ.")
|
||||
return
|
||||
else:
|
||||
print("No GPU detected. AutoGPTQ installation requires a GPU with CUDA or ROCm support.")
|
||||
return
|
||||
|
||||
# Execute the installation command
|
||||
try:
|
||||
print(f"Installing AutoGPTQ with command: {' '.join(base_command)}")
|
||||
subprocess.check_call(base_command)
|
||||
except Exception as e:
|
||||
print(f"Failed to install AutoGPTQ: {e}")
|
||||
|
||||
config = None
|
||||
|
||||
def is_logging_enabled():
|
||||
config = get_extension_config()
|
||||
if "logging" not in config:
|
||||
return False
|
||||
return config["logging"]
|
||||
|
||||
def log(message, type=None, always=False, name=None):
|
||||
if not always and not is_logging_enabled():
|
||||
return
|
||||
|
||||
if type is not None:
|
||||
message = f"[{type}] {message}"
|
||||
|
||||
if name is None:
|
||||
name = get_extension_config()["name"]
|
||||
|
||||
print(f"(vlmnodes:{name}) {message}")
|
||||
|
||||
def get_ext_dir(subpath=None, mkdir=False):
|
||||
dir = os.path.dirname(__file__)
|
||||
if subpath is not None:
|
||||
dir = os.path.join(dir, subpath)
|
||||
|
||||
dir = os.path.abspath(dir)
|
||||
|
||||
if mkdir and not os.path.exists(dir):
|
||||
os.makedirs(dir)
|
||||
return dir
|
||||
|
||||
def get_comfy_dir(subpath=None, mkdir=False):
|
||||
dir = os.path.dirname(inspect.getfile(PromptServer))
|
||||
if subpath is not None:
|
||||
dir = os.path.join(dir, subpath)
|
||||
|
||||
dir = os.path.abspath(dir)
|
||||
|
||||
if mkdir and not os.path.exists(dir):
|
||||
os.makedirs(dir)
|
||||
return dir
|
||||
|
||||
def get_web_ext_dir():
|
||||
config = get_extension_config()
|
||||
name = config["name"]
|
||||
dir = get_comfy_dir("web/extensions/vlmnodes")
|
||||
if not os.path.exists(dir):
|
||||
os.makedirs(dir)
|
||||
dir = os.path.join(dir, name)
|
||||
return dir
|
||||
|
||||
def get_extension_config(reload=False):
|
||||
global config
|
||||
if reload == False and config is not None:
|
||||
return config
|
||||
|
||||
config_path = get_ext_dir("vlmnodes.json")
|
||||
if not os.path.exists(config_path):
|
||||
log("Missing vlmnodes.json, this extension may not work correctly. Please reinstall the extension.",
|
||||
type="ERROR", always=True, name="???")
|
||||
print(f"Extension path: {get_ext_dir()}")
|
||||
return {"name": "Unknown", "version": -1}
|
||||
with open(config_path, "r") as f:
|
||||
config = json.loads(f.read())
|
||||
return config
|
||||
|
||||
def link_js(src, dst):
|
||||
src = os.path.abspath(src)
|
||||
dst = os.path.abspath(dst)
|
||||
if os.name == "nt":
|
||||
try:
|
||||
import _winapi
|
||||
_winapi.CreateJunction(src, dst)
|
||||
return True
|
||||
except:
|
||||
pass
|
||||
try:
|
||||
os.symlink(src, dst)
|
||||
return True
|
||||
except:
|
||||
import logging
|
||||
logging.exception('')
|
||||
return False
|
||||
|
||||
def is_junction(path):
|
||||
if os.name != "nt":
|
||||
return False
|
||||
try:
|
||||
return bool(os.readlink(path))
|
||||
except OSError:
|
||||
return False
|
||||
|
||||
def install_js():
|
||||
src_dir = get_ext_dir("js")
|
||||
if not os.path.exists(src_dir):
|
||||
log("No JS")
|
||||
return
|
||||
|
||||
dst_dir = get_web_ext_dir()
|
||||
|
||||
if os.path.exists(dst_dir):
|
||||
if os.path.islink(dst_dir) or is_junction(dst_dir):
|
||||
log("JS already linked")
|
||||
return
|
||||
elif link_js(src_dir, dst_dir):
|
||||
log("JS linked")
|
||||
return
|
||||
|
||||
log("Copying JS files")
|
||||
shutil.copytree(src_dir, dst_dir, dirs_exist_ok=True)
|
||||
|
||||
def init(check_imports=None):
|
||||
log("Init")
|
||||
|
||||
if check_imports is not None:
|
||||
import importlib.util
|
||||
for imp in check_imports:
|
||||
spec = importlib.util.find_spec(imp)
|
||||
if spec is None:
|
||||
log(f"{imp} is required, please check requirements are installed.",
|
||||
type="ERROR", always=True)
|
||||
return False
|
||||
|
||||
install_js()
|
||||
return True
|
||||
|
||||
def get_async_loop():
|
||||
loop = None
|
||||
try:
|
||||
loop = asyncio.get_event_loop()
|
||||
except:
|
||||
loop = asyncio.new_event_loop()
|
||||
asyncio.set_event_loop(loop)
|
||||
return loop
|
||||
|
||||
def get_http_session():
|
||||
loop = get_async_loop()
|
||||
return aiohttp.ClientSession(loop=loop)
|
||||
|
||||
async def download(url, stream, update_callback=None, session=None):
|
||||
close_session = False
|
||||
if session is None:
|
||||
close_session = True
|
||||
session = get_http_session()
|
||||
try:
|
||||
async with session.get(url) as response:
|
||||
size = int(response.headers.get('content-length', 0)) or None
|
||||
|
||||
with tqdm(
|
||||
unit='B', unit_scale=True, miniters=1, desc=url.split('/')[-1], total=size,
|
||||
) as progressbar:
|
||||
perc = 0
|
||||
async for chunk in response.content.iter_chunked(2048):
|
||||
stream.write(chunk)
|
||||
progressbar.update(len(chunk))
|
||||
if update_callback is not None and progressbar.total is not None and progressbar.total != 0:
|
||||
last = perc
|
||||
perc = round(progressbar.n / progressbar.total, 2)
|
||||
if perc != last:
|
||||
last = perc
|
||||
await update_callback(perc)
|
||||
finally:
|
||||
if close_session and session is not None:
|
||||
await session.close()
|
||||
|
||||
async def download_to_file(url, destination, update_callback=None, is_ext_subpath=True, session=None):
|
||||
if is_ext_subpath:
|
||||
destination = get_ext_dir(destination)
|
||||
with open(destination, mode='wb') as f:
|
||||
download(url, f, update_callback, session)
|
||||
|
||||
def is_inside_dir(root_dir, check_path):
|
||||
root_dir = os.path.abspath(root_dir)
|
||||
if not os.path.isabs(check_path):
|
||||
check_path = os.path.abspath(os.path.join(root_dir, check_path))
|
||||
return os.path.commonpath([check_path, root_dir]) == root_dir
|
||||
|
||||
def get_child_dir(root_dir, child_path, throw_if_outside=True):
|
||||
child_path = os.path.abspath(os.path.join(root_dir, child_path))
|
||||
if is_inside_dir(root_dir, child_path):
|
||||
return child_path
|
||||
if throw_if_outside:
|
||||
raise NotADirectoryError(
|
||||
"Saving outside the target folder is not allowed.")
|
||||
return None
|
||||
@@ -1,42 +0,0 @@
|
||||
import { app } from "/scripts/app.js";
|
||||
import { ComfyWidgets } from "/scripts/widgets.js";
|
||||
|
||||
app.registerExtension({
|
||||
name: "n.JsonToText",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData, app) {
|
||||
|
||||
if (nodeData.name === "JsonToText") {
|
||||
console.warn("JsonToText");
|
||||
|
||||
const onExecuted = nodeType.prototype.onExecuted;
|
||||
|
||||
nodeType.prototype.onExecuted = function (message) {
|
||||
if (this.widgets) {
|
||||
for (let i = 1; i < this.widgets.length; i++) {
|
||||
this.widgets[i].onRemove?.();
|
||||
}
|
||||
this.widgets.length = 1;
|
||||
}
|
||||
|
||||
// Call the original onExecuted method if it exists.
|
||||
onExecuted?.apply(this, arguments);
|
||||
|
||||
// Check if the "text" widget already exists.
|
||||
let textWidget = this.widgets.find(w => w.name === "newtext");
|
||||
if (!textWidget) {
|
||||
// If the "text" widget does not exist, create it.
|
||||
textWidget = ComfyWidgets["STRING"](this, "newtext", ["STRING", { multiline: true }], app).widget;
|
||||
}
|
||||
|
||||
// Generate a random number and set it as the value of the "text" widget.
|
||||
|
||||
textWidget.inputEl.readOnly = true;
|
||||
textWidget.inputEl.style.opacity = 0.6;
|
||||
textWidget.value = message["text"].join("");
|
||||
// change color of the widget
|
||||
console.log(message)
|
||||
|
||||
};
|
||||
}
|
||||
},
|
||||
});
|
||||
@@ -1,42 +0,0 @@
|
||||
import { app } from "/scripts/app.js";
|
||||
import { ComfyWidgets } from "/scripts/widgets.js";
|
||||
|
||||
app.registerExtension({
|
||||
name: "n.ViewText",
|
||||
async beforeRegisterNodeDef(nodeType, nodeData, app) {
|
||||
|
||||
if (nodeData.name === "ViewText") {
|
||||
console.warn("ViewText");
|
||||
|
||||
const onExecuted = nodeType.prototype.onExecuted;
|
||||
|
||||
nodeType.prototype.onExecuted = function (message) {
|
||||
if (this.widgets) {
|
||||
for (let i = 1; i < this.widgets.length; i++) {
|
||||
this.widgets[i].onRemove?.();
|
||||
}
|
||||
this.widgets.length = 1;
|
||||
}
|
||||
|
||||
// Call the original onExecuted method if it exists.
|
||||
onExecuted?.apply(this, arguments);
|
||||
|
||||
// Check if the "text" widget already exists.
|
||||
let textWidget = this.widgets.find(w => w.name === "new_text");
|
||||
if (!textWidget) {
|
||||
// If the "text" widget does not exist, create it.
|
||||
textWidget = ComfyWidgets["STRING"](this, "new_text", ["STRING", { multiline: true }], app).widget;
|
||||
}
|
||||
|
||||
// Generate a random number and set it as the value of the "text" widget.
|
||||
|
||||
textWidget.inputEl.readOnly = true;
|
||||
textWidget.inputEl.style.opacity = 0.6;
|
||||
textWidget.value = message["text"].join("");
|
||||
// change color of the widget
|
||||
console.log(message)
|
||||
|
||||
};
|
||||
}
|
||||
},
|
||||
});
|
||||
@@ -0,0 +1,279 @@
|
||||
"""Model-agnostic acceleration utilities for image and video VLM workflows.
|
||||
|
||||
These nodes reduce visual work *before* it reaches a model. They are therefore
|
||||
portable across Transformers, llama.cpp, Photon, hosted APIs, CUDA, ROCm, MPS,
|
||||
XPU, and CPU runtimes. No model is downloaded and no global PyTorch setting is
|
||||
changed when this module is imported or executed.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
import math
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as functional
|
||||
|
||||
RESIZE_QUALITY = (
|
||||
"Fast (area)",
|
||||
"Quality (bicubic)",
|
||||
)
|
||||
PERFORMANCE_PROFILES = {
|
||||
"Live / robotics": {
|
||||
"max_frames": 24,
|
||||
"max_megapixels": 0.5,
|
||||
"max_edge": 896,
|
||||
"batch_size": 8,
|
||||
"unload_after": False,
|
||||
},
|
||||
"Fast video": {
|
||||
"max_frames": 48,
|
||||
"max_megapixels": 0.75,
|
||||
"max_edge": 1024,
|
||||
"batch_size": 8,
|
||||
"unload_after": False,
|
||||
},
|
||||
"Balanced": {
|
||||
"max_frames": 64,
|
||||
"max_megapixels": 1.0,
|
||||
"max_edge": 1344,
|
||||
"batch_size": 4,
|
||||
"unload_after": False,
|
||||
},
|
||||
"High detail": {
|
||||
"max_frames": 96,
|
||||
"max_megapixels": 2.0,
|
||||
"max_edge": 2048,
|
||||
"batch_size": 2,
|
||||
"unload_after": False,
|
||||
},
|
||||
"Low VRAM handoff": {
|
||||
"max_frames": 32,
|
||||
"max_megapixels": 0.75,
|
||||
"max_edge": 1024,
|
||||
"batch_size": 1,
|
||||
"unload_after": True,
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
def _json(value: Any) -> str:
|
||||
return json.dumps(
|
||||
value,
|
||||
ensure_ascii=False,
|
||||
allow_nan=False,
|
||||
sort_keys=True,
|
||||
indent=2,
|
||||
)
|
||||
|
||||
|
||||
def _validate_image_batch(images: torch.Tensor) -> tuple[torch.Tensor, bool]:
|
||||
if not isinstance(images, torch.Tensor):
|
||||
raise TypeError("images must be a ComfyUI IMAGE tensor.")
|
||||
single = images.ndim == 3
|
||||
value = images.unsqueeze(0) if single else images
|
||||
if value.ndim != 4:
|
||||
raise ValueError(
|
||||
f"Expected an HWC/BHWC or CHW/BCHW IMAGE tensor, got {tuple(images.shape)}."
|
||||
)
|
||||
if value.shape[-1] in (1, 3, 4):
|
||||
return value, single
|
||||
if value.shape[1] in (1, 3, 4):
|
||||
return value.permute(0, 2, 3, 1), single
|
||||
raise ValueError(f"Unsupported image channel shape: {tuple(images.shape)}.")
|
||||
|
||||
|
||||
def optimize_image_pixels(
|
||||
images: torch.Tensor,
|
||||
*,
|
||||
max_megapixels: float,
|
||||
max_edge: int,
|
||||
multiple: int,
|
||||
resize_quality: str,
|
||||
) -> tuple[torch.Tensor, dict[str, Any]]:
|
||||
"""Downscale a batch once to a bounded visual-token pixel budget."""
|
||||
|
||||
value, single = _validate_image_batch(images)
|
||||
if not math.isfinite(float(max_megapixels)) or max_megapixels <= 0:
|
||||
raise ValueError("max_megapixels must be finite and positive.")
|
||||
if not isinstance(max_edge, int) or max_edge < 32:
|
||||
raise ValueError("max_edge must be at least 32 pixels.")
|
||||
if multiple not in {1, 14, 28, 32}:
|
||||
raise ValueError("multiple must be one of 1, 14, 28, or 32.")
|
||||
if resize_quality not in RESIZE_QUALITY:
|
||||
raise ValueError(f"Unknown resize quality {resize_quality!r}.")
|
||||
|
||||
height, width = int(value.shape[1]), int(value.shape[2])
|
||||
pixel_budget = float(max_megapixels) * 1_000_000
|
||||
scale = min(
|
||||
1.0,
|
||||
float(max_edge) / max(width, height),
|
||||
math.sqrt(pixel_budget / (width * height)),
|
||||
)
|
||||
|
||||
def bounded_dimension(dimension: int) -> int:
|
||||
target = max(1, math.floor(dimension * scale))
|
||||
if multiple == 1 or target < multiple:
|
||||
return target
|
||||
return max(multiple, (target // multiple) * multiple)
|
||||
|
||||
output_width = bounded_dimension(width)
|
||||
output_height = bounded_dimension(height)
|
||||
output = value
|
||||
resized_image = (output_height, output_width) != (height, width)
|
||||
if resized_image:
|
||||
nchw = value.permute(0, 3, 1, 2)
|
||||
if resize_quality == "Fast (area)":
|
||||
resized = functional.interpolate(
|
||||
nchw,
|
||||
size=(output_height, output_width),
|
||||
mode="area",
|
||||
)
|
||||
else:
|
||||
resized = functional.interpolate(
|
||||
nchw,
|
||||
size=(output_height, output_width),
|
||||
mode="bicubic",
|
||||
align_corners=False,
|
||||
antialias=True,
|
||||
)
|
||||
output = resized.permute(0, 2, 3, 1).clamp(0.0, 1.0)
|
||||
report = {
|
||||
"frames": int(value.shape[0]),
|
||||
"input_width": width,
|
||||
"input_height": height,
|
||||
"output_width": output_width,
|
||||
"output_height": output_height,
|
||||
"input_pixels_per_frame": width * height,
|
||||
"output_pixels_per_frame": output_width * output_height,
|
||||
"visual_work_reduction": (
|
||||
(width * height) / max(1, output_width * output_height)
|
||||
),
|
||||
"resized": resized_image,
|
||||
"multiple": multiple,
|
||||
"quality": resize_quality,
|
||||
}
|
||||
if not resized_image:
|
||||
return images, report
|
||||
return (output[0] if single else output), report
|
||||
|
||||
|
||||
class VLMPerformanceProfile:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"profile": (
|
||||
tuple(PERFORMANCE_PROFILES),
|
||||
{"default": "Balanced"},
|
||||
)
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("INT", "FLOAT", "INT", "INT", "BOOLEAN", "STRING")
|
||||
RETURN_NAMES = (
|
||||
"max_frames",
|
||||
"max_megapixels",
|
||||
"max_edge",
|
||||
"batch_size",
|
||||
"unload_after",
|
||||
"profile_json",
|
||||
)
|
||||
FUNCTION = "profile"
|
||||
CATEGORY = "VLM Nodes/Performance"
|
||||
DESCRIPTION = (
|
||||
"Portable speed/quality presets for the sampler, pixel optimizer, "
|
||||
"and VLM batch inputs. The profile never changes global runtime state."
|
||||
)
|
||||
|
||||
def profile(self, profile):
|
||||
values = dict(PERFORMANCE_PROFILES[profile])
|
||||
values["profile"] = profile
|
||||
return (
|
||||
values["max_frames"],
|
||||
values["max_megapixels"],
|
||||
values["max_edge"],
|
||||
values["batch_size"],
|
||||
values["unload_after"],
|
||||
_json(values),
|
||||
)
|
||||
|
||||
|
||||
class VLMImagePixelBudget:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"images": ("IMAGE",),
|
||||
"max_megapixels": (
|
||||
"FLOAT",
|
||||
{"default": 1.0, "min": 0.01, "max": 64.0, "step": 0.05},
|
||||
),
|
||||
"max_edge": (
|
||||
"INT",
|
||||
{"default": 1344, "min": 32, "max": 16384, "step": 14},
|
||||
),
|
||||
"multiple": (
|
||||
("1", "14", "28", "32"),
|
||||
{
|
||||
"default": "14",
|
||||
"tooltip": (
|
||||
"14/28 suit common VLM vision patches; 32 suits "
|
||||
"many detector backbones. Use 1 for arbitrary sizes."
|
||||
),
|
||||
},
|
||||
),
|
||||
"resize_quality": (
|
||||
RESIZE_QUALITY,
|
||||
{"default": "Fast (area)"},
|
||||
),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("IMAGE", "INT", "INT", "STRING")
|
||||
RETURN_NAMES = (
|
||||
"optimized_images",
|
||||
"width",
|
||||
"height",
|
||||
"optimization_report",
|
||||
)
|
||||
FUNCTION = "optimize"
|
||||
CATEGORY = "VLM Nodes/Performance"
|
||||
DESCRIPTION = (
|
||||
"Apply one portable pixel budget before any VLM, avoiding repeated "
|
||||
"high-resolution visual-token work while preserving aspect ratio."
|
||||
)
|
||||
|
||||
def optimize(
|
||||
self,
|
||||
images,
|
||||
max_megapixels,
|
||||
max_edge,
|
||||
multiple,
|
||||
resize_quality,
|
||||
):
|
||||
output, report = optimize_image_pixels(
|
||||
images,
|
||||
max_megapixels=float(max_megapixels),
|
||||
max_edge=int(max_edge),
|
||||
multiple=int(multiple),
|
||||
resize_quality=resize_quality,
|
||||
)
|
||||
return (
|
||||
output,
|
||||
report["output_width"],
|
||||
report["output_height"],
|
||||
_json(report),
|
||||
)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"VLMPerformanceProfile": VLMPerformanceProfile,
|
||||
"VLMImagePixelBudget": VLMImagePixelBudget,
|
||||
}
|
||||
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"VLMPerformanceProfile": "VLM Performance Profile",
|
||||
"VLMImagePixelBudget": "VLM Image Pixel Budget",
|
||||
}
|
||||
@@ -0,0 +1,230 @@
|
||||
"""Lazy AudioLDM2 generation with legacy and standard ComfyUI AUDIO outputs."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
from pathlib import Path
|
||||
|
||||
import folder_paths
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
execution_device,
|
||||
require_module,
|
||||
reserve_external_vram,
|
||||
snapshot_download,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
|
||||
class AnyType(str):
|
||||
def __ne__(self, other):
|
||||
return False
|
||||
|
||||
|
||||
ANY = AnyType("*")
|
||||
|
||||
|
||||
class AudioLDM2Predictor:
|
||||
def __init__(self, cpu_offload=True):
|
||||
diffusers = require_module("diffusers")
|
||||
path = snapshot_download(
|
||||
"cvssp/audioldm2",
|
||||
"audioldm2",
|
||||
ignore_patterns=["*.bin", "*.jpg", "*.png"],
|
||||
)
|
||||
self.device = execution_device()
|
||||
dtype = torch_dtype("float16", self.device)
|
||||
if self.device.type != "cpu":
|
||||
reserve_external_vram(8 * 1024**3)
|
||||
self.pipeline = diffusers.AudioLDM2Pipeline.from_pretrained(
|
||||
path, torch_dtype=dtype
|
||||
)
|
||||
# Accelerate's model CPU offload is currently reliable on the CUDA API,
|
||||
# which covers both NVIDIA CUDA and AMD ROCm PyTorch builds.
|
||||
if self.device.type == "cuda" and cpu_offload:
|
||||
require_module("accelerate")
|
||||
self.pipeline.enable_model_cpu_offload()
|
||||
else:
|
||||
self.pipeline.to(self.device)
|
||||
|
||||
def close(self):
|
||||
self.pipeline = None
|
||||
import gc
|
||||
|
||||
gc.collect()
|
||||
try:
|
||||
import comfy.model_management as model_management
|
||||
|
||||
model_management.soft_empty_cache()
|
||||
except Exception:
|
||||
pass
|
||||
|
||||
def generate(self, text, negative, duration, guidance, seed, count, steps):
|
||||
# MPS generators are not supported by every PyTorch/Diffusers pairing.
|
||||
# A CPU generator remains deterministic and works with every pipeline.
|
||||
generator_device = (
|
||||
self.device if self.device.type in {"cuda", "xpu"} else "cpu"
|
||||
)
|
||||
generator = torch.Generator(device=generator_device).manual_seed(
|
||||
int(seed)
|
||||
)
|
||||
audios = self.pipeline(
|
||||
text,
|
||||
negative_prompt=negative or None,
|
||||
audio_length_in_s=float(duration),
|
||||
guidance_scale=float(guidance),
|
||||
num_inference_steps=int(steps),
|
||||
num_waveforms_per_prompt=int(count),
|
||||
generator=generator,
|
||||
).audios
|
||||
array = np.asarray(audios, dtype=np.float32)
|
||||
if array.ndim == 1:
|
||||
array = array[None, :]
|
||||
native_rate = int(
|
||||
getattr(
|
||||
getattr(getattr(self.pipeline, "vae", None), "config", None),
|
||||
"sampling_rate",
|
||||
16000,
|
||||
)
|
||||
)
|
||||
return array, native_rate
|
||||
|
||||
|
||||
class AudioLDM2Node(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"text": ("STRING", {"default": "", "multiline": True}),
|
||||
"negative_prompt": (
|
||||
"STRING",
|
||||
{"default": "", "multiline": True},
|
||||
),
|
||||
"duration": (
|
||||
"INT",
|
||||
{"default": 10, "min": 1, "max": 60},
|
||||
),
|
||||
"guidance_scale": (
|
||||
"FLOAT",
|
||||
{"default": 3.5, "min": 0.1, "max": 20.0, "step": 0.1},
|
||||
),
|
||||
"seed": ("INT", {"default": 42, "min": 0}),
|
||||
"n_candidates": (
|
||||
"INT",
|
||||
{"default": 1, "min": 1, "max": 10},
|
||||
),
|
||||
"sample_rate": (
|
||||
"INT",
|
||||
{"default": 16000, "min": 8000, "max": 48000},
|
||||
),
|
||||
"extension": (["wav", "flac"],),
|
||||
},
|
||||
"optional": {
|
||||
"steps": ("INT", {"default": 100, "min": 10, "max": 500}),
|
||||
"cpu_offload": ("BOOLEAN", {"default": True}),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_NAMES = ("wave_form", "sample_rate", "audio")
|
||||
RETURN_TYPES = (ANY, "INT", "AUDIO")
|
||||
OUTPUT_NODE = True
|
||||
FUNCTION = "generate_audio_final"
|
||||
CATEGORY = "VLM Nodes/Audio"
|
||||
|
||||
def generate_audio_final(
|
||||
self,
|
||||
text,
|
||||
negative_prompt,
|
||||
duration,
|
||||
guidance_scale,
|
||||
sample_rate,
|
||||
seed,
|
||||
n_candidates,
|
||||
extension,
|
||||
steps=100,
|
||||
cpu_offload=True,
|
||||
unload_after=False,
|
||||
):
|
||||
del extension
|
||||
predictor = self.get_or_create_model(
|
||||
("audioldm2", bool(cpu_offload)),
|
||||
lambda: AudioLDM2Predictor(cpu_offload),
|
||||
)
|
||||
try:
|
||||
waveforms, native_rate = predictor.generate(
|
||||
text,
|
||||
negative_prompt,
|
||||
duration,
|
||||
guidance_scale,
|
||||
seed,
|
||||
n_candidates,
|
||||
steps,
|
||||
)
|
||||
if int(sample_rate) != native_rate:
|
||||
samples = torch.from_numpy(waveforms).unsqueeze(1)
|
||||
target_length = round(
|
||||
samples.shape[-1] * int(sample_rate) / native_rate
|
||||
)
|
||||
waveforms = (
|
||||
torch.nn.functional.interpolate(
|
||||
samples,
|
||||
size=target_length,
|
||||
mode="linear",
|
||||
align_corners=False,
|
||||
)
|
||||
.squeeze(1)
|
||||
.numpy()
|
||||
)
|
||||
# Standard Comfy AUDIO is [batch, channels, samples].
|
||||
audio = {
|
||||
"waveform": torch.from_numpy(waveforms).unsqueeze(1),
|
||||
"sample_rate": int(sample_rate),
|
||||
}
|
||||
return (waveforms[0].tolist(), int(sample_rate), audio)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
class SaveAudioNode:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"waveforms": (ANY,),
|
||||
"sample_rate": ("INT",),
|
||||
"extension": (["wav", "flac"],),
|
||||
"filename": ("STRING", {"default": "audio"}),
|
||||
}
|
||||
}
|
||||
|
||||
RETURN_TYPES = ()
|
||||
FUNCTION = "save_audio"
|
||||
CATEGORY = "VLM Nodes/Audio"
|
||||
OUTPUT_NODE = True
|
||||
|
||||
def save_audio(self, waveforms, sample_rate, extension, filename):
|
||||
soundfile = require_module("soundfile")
|
||||
safe_name = Path(filename).name.strip() or "audio"
|
||||
output = Path(folder_paths.output_directory)
|
||||
output.mkdir(parents=True, exist_ok=True)
|
||||
base = output / safe_name
|
||||
path = base.with_suffix(f".{extension}")
|
||||
counter = 2
|
||||
while path.exists():
|
||||
path = output / f"{safe_name}_{counter:05d}.{extension}"
|
||||
counter += 1
|
||||
soundfile.write(path, np.asarray(waveforms), int(sample_rate))
|
||||
return ()
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"AudioLDM2Node": AudioLDM2Node,
|
||||
"SaveAudioNode": SaveAudioNode,
|
||||
}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"AudioLDM2Node": "AudioLDM2",
|
||||
"SaveAudioNode": "Save Audio",
|
||||
}
|
||||
@@ -0,0 +1,35 @@
|
||||
"""A zero-download runtime report for portable support requests."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
|
||||
from .runtime import runtime_diagnostics
|
||||
|
||||
|
||||
class VLMRuntimeDiagnostics:
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {"required": {}}
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
RETURN_NAMES = ("runtime_report",)
|
||||
FUNCTION = "report"
|
||||
CATEGORY = "VLM Nodes/Diagnostics"
|
||||
OUTPUT_NODE = True
|
||||
|
||||
def report(self):
|
||||
return (
|
||||
json.dumps(
|
||||
runtime_diagnostics(),
|
||||
ensure_ascii=False,
|
||||
indent=2,
|
||||
sort_keys=True,
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"VLMRuntimeDiagnostics": VLMRuntimeDiagnostics}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"VLMRuntimeDiagnostics": "VLM Runtime Diagnostics"
|
||||
}
|
||||
@@ -0,0 +1,510 @@
|
||||
"""Florence-2 multitask caption, OCR, detection and segmentation node."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import hashlib
|
||||
import json
|
||||
import math
|
||||
from dataclasses import dataclass
|
||||
from numbers import Real
|
||||
|
||||
import torch
|
||||
from PIL import Image, ImageDraw
|
||||
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
batch_text,
|
||||
inference_context,
|
||||
model_device,
|
||||
move_inputs,
|
||||
pil_mask_to_tensor,
|
||||
pil_to_tensor,
|
||||
require_module,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
|
||||
MODELS = {
|
||||
"Florence-2 base FT (fast)": "florence-community/Florence-2-base-ft",
|
||||
"Florence-2 large FT (recommended)": ("florence-community/Florence-2-large-ft"),
|
||||
}
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class FlorenceTaskSpec:
|
||||
"""Declarative contract for one official Florence-2 task."""
|
||||
|
||||
token: str
|
||||
input_kind: str
|
||||
output_kind: str
|
||||
|
||||
|
||||
TASKS = {
|
||||
"Caption": FlorenceTaskSpec("<CAPTION>", "none", "text"),
|
||||
"Detailed caption": FlorenceTaskSpec("<DETAILED_CAPTION>", "none", "text"),
|
||||
"More detailed caption": FlorenceTaskSpec(
|
||||
"<MORE_DETAILED_CAPTION>", "none", "text"
|
||||
),
|
||||
"OCR": FlorenceTaskSpec("<OCR>", "none", "text"),
|
||||
"OCR with regions": FlorenceTaskSpec("<OCR_WITH_REGION>", "none", "quad_boxes"),
|
||||
"Object detection": FlorenceTaskSpec("<OD>", "none", "boxes"),
|
||||
"Dense region caption": FlorenceTaskSpec("<DENSE_REGION_CAPTION>", "none", "boxes"),
|
||||
"Caption to phrase grounding": FlorenceTaskSpec(
|
||||
"<CAPTION_TO_PHRASE_GROUNDING>", "text", "boxes"
|
||||
),
|
||||
"Referring expression segmentation": FlorenceTaskSpec(
|
||||
"<REFERRING_EXPRESSION_SEGMENTATION>", "text", "polygons"
|
||||
),
|
||||
"Region to segmentation": FlorenceTaskSpec(
|
||||
"<REGION_TO_SEGMENTATION>", "region", "polygons"
|
||||
),
|
||||
"Open vocabulary detection": FlorenceTaskSpec(
|
||||
"<OPEN_VOCABULARY_DETECTION>", "text", "mixed"
|
||||
),
|
||||
"Region to category": FlorenceTaskSpec("<REGION_TO_CATEGORY>", "region", "text"),
|
||||
"Region to description": FlorenceTaskSpec(
|
||||
"<REGION_TO_DESCRIPTION>", "region", "text"
|
||||
),
|
||||
"Region to OCR": FlorenceTaskSpec("<REGION_TO_OCR>", "region", "text"),
|
||||
"Region proposals": FlorenceTaskSpec("<REGION_PROPOSAL>", "none", "boxes"),
|
||||
}
|
||||
|
||||
|
||||
def _clean_decoded_text(value):
|
||||
"""Remove generation wrappers without discarding Florence location tokens."""
|
||||
|
||||
text = str(value)
|
||||
for token in ("<s>", "</s>", "<pad>"):
|
||||
text = text.replace(token, "")
|
||||
return text.strip()
|
||||
|
||||
|
||||
def _select_region(region, image_index, batch_size):
|
||||
"""Select one core BOUNDING_BOX for the current image.
|
||||
|
||||
Core primitive boxes are dictionaries. Detection nodes may emit either a
|
||||
flat per-image list or a nested batch list, so both common shapes are
|
||||
accepted while ambiguous multi-region inputs fail explicitly.
|
||||
"""
|
||||
|
||||
if region is None or isinstance(region, dict):
|
||||
return region
|
||||
if not isinstance(region, (list, tuple)):
|
||||
raise TypeError("region must be a core BOUNDING_BOX dictionary.")
|
||||
if not region:
|
||||
return None
|
||||
|
||||
if all(isinstance(item, dict) for item in region):
|
||||
if len(region) == 1:
|
||||
return region[0]
|
||||
if len(region) == batch_size:
|
||||
return region[image_index]
|
||||
raise ValueError("Region tasks require exactly one BOUNDING_BOX per image.")
|
||||
|
||||
if len(region) != batch_size:
|
||||
raise ValueError("Batched BOUNDING_BOX input must contain one entry per image.")
|
||||
frame_regions = region[image_index]
|
||||
if isinstance(frame_regions, dict):
|
||||
return frame_regions
|
||||
if not isinstance(frame_regions, (list, tuple)) or len(frame_regions) != 1:
|
||||
raise ValueError(
|
||||
"Region tasks require exactly one BOUNDING_BOX per image; "
|
||||
"select a detection before connecting it."
|
||||
)
|
||||
if not isinstance(frame_regions[0], dict):
|
||||
raise TypeError("Each BOUNDING_BOX entry must be a dictionary.")
|
||||
return frame_regions[0]
|
||||
|
||||
|
||||
def _encode_region(region, image_size):
|
||||
"""Encode an absolute-pixel core BOUNDING_BOX as Florence location tokens."""
|
||||
|
||||
if not isinstance(region, dict):
|
||||
raise TypeError("region must be a core BOUNDING_BOX dictionary.")
|
||||
|
||||
try:
|
||||
x = float(region["x"])
|
||||
y = float(region["y"])
|
||||
box_width = float(region["width"])
|
||||
box_height = float(region["height"])
|
||||
except KeyError as exc:
|
||||
raise ValueError("region must contain x, y, width, and height.") from exc
|
||||
except (TypeError, ValueError) as exc:
|
||||
raise ValueError("region coordinates must be numeric.") from exc
|
||||
|
||||
values = (x, y, box_width, box_height)
|
||||
if not all(math.isfinite(value) for value in values):
|
||||
raise ValueError("region coordinates must be finite.")
|
||||
if box_width <= 0 or box_height <= 0:
|
||||
raise ValueError("region width and height must be greater than zero.")
|
||||
|
||||
image_width, image_height = image_size
|
||||
if image_width <= 0 or image_height <= 0:
|
||||
raise ValueError("image dimensions must be greater than zero.")
|
||||
|
||||
x0 = max(0.0, min(float(image_width), x))
|
||||
y0 = max(0.0, min(float(image_height), y))
|
||||
x1 = max(0.0, min(float(image_width), x + box_width))
|
||||
y1 = max(0.0, min(float(image_height), y + box_height))
|
||||
if x1 <= x0 or y1 <= y0:
|
||||
raise ValueError("region does not overlap the input image.")
|
||||
|
||||
coordinates = (
|
||||
x0 / image_width,
|
||||
y0 / image_height,
|
||||
x1 / image_width,
|
||||
y1 / image_height,
|
||||
)
|
||||
bins = [
|
||||
max(0, min(999, math.floor(coordinate * 1000))) for coordinate in coordinates
|
||||
]
|
||||
return "".join(f"<loc_{value}>" for value in bins)
|
||||
|
||||
|
||||
def _task_extra_input(task_name, text_input, region, image_size):
|
||||
"""Validate and prepare the optional suffix for a Florence task prompt."""
|
||||
|
||||
try:
|
||||
spec = TASKS[task_name]
|
||||
except KeyError as exc:
|
||||
raise ValueError(f"Unsupported Florence-2 task: {task_name}") from exc
|
||||
|
||||
text = (text_input or "").strip()
|
||||
if spec.input_kind == "none":
|
||||
if text:
|
||||
raise ValueError(f"{task_name} does not accept text input.")
|
||||
if region is not None:
|
||||
raise ValueError(f"{task_name} does not accept a region input.")
|
||||
return ""
|
||||
if spec.input_kind == "text":
|
||||
if not text:
|
||||
raise ValueError(f"{task_name} requires text input.")
|
||||
if region is not None:
|
||||
raise ValueError(f"{task_name} does not accept a region input.")
|
||||
return text
|
||||
if spec.input_kind == "region":
|
||||
if text:
|
||||
raise ValueError(
|
||||
f"{task_name} uses the region input and does not accept text."
|
||||
)
|
||||
if region is None:
|
||||
raise ValueError(f"{task_name} requires a connected BOUNDING_BOX region.")
|
||||
return _encode_region(region, image_size)
|
||||
raise RuntimeError(f"Unknown Florence task input kind: {spec.input_kind}")
|
||||
|
||||
|
||||
class FlorencePredictor:
|
||||
def __init__(self, model_label):
|
||||
transformers = require_module("transformers")
|
||||
repo_id = MODELS[model_label]
|
||||
path = snapshot_download(
|
||||
repo_id,
|
||||
f"florence2/{repo_id.replace('/', '--')}",
|
||||
ignore_patterns=["*.bin"],
|
||||
)
|
||||
self.dtype = torch_dtype("float16")
|
||||
self.processor = transformers.Florence2Processor.from_pretrained(path)
|
||||
model = transformers.Florence2ForConditionalGeneration.from_pretrained(
|
||||
path,
|
||||
dtype=self.dtype,
|
||||
)
|
||||
model.eval()
|
||||
self.handle = ManagedTorchModel(model, processor=self.processor)
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
self.processor = None
|
||||
|
||||
def run(self, image, task_token, text, max_new_tokens, beams):
|
||||
prompt = task_token + (text.strip() if text.strip() else "")
|
||||
inputs = self.processor(text=prompt, images=image, return_tensors="pt")
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
inputs = move_inputs(inputs, device, floating_dtype=self.dtype)
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
generated = model.generate(
|
||||
**inputs,
|
||||
max_new_tokens=int(max_new_tokens),
|
||||
num_beams=int(beams),
|
||||
do_sample=False,
|
||||
early_stopping=int(beams) > 1,
|
||||
)
|
||||
raw = self.processor.batch_decode(generated, skip_special_tokens=False)[0]
|
||||
parsed = self.processor.post_process_generation(
|
||||
raw, task=task_token, image_size=image.size
|
||||
)
|
||||
return raw, parsed
|
||||
|
||||
|
||||
def _json_default(value):
|
||||
if hasattr(value, "tolist"):
|
||||
return value.tolist()
|
||||
return str(value)
|
||||
|
||||
|
||||
_SPATIAL_KEYS = frozenset(
|
||||
{
|
||||
"bboxes",
|
||||
"quad_boxes",
|
||||
"polygons",
|
||||
"labels",
|
||||
"bboxes_labels",
|
||||
"polygons_labels",
|
||||
}
|
||||
)
|
||||
|
||||
|
||||
def _spatial_result(parsed):
|
||||
if not isinstance(parsed, dict):
|
||||
return {}
|
||||
if _SPATIAL_KEYS.intersection(parsed):
|
||||
return parsed
|
||||
result = next(iter(parsed.values()), {})
|
||||
return result if isinstance(result, dict) else {}
|
||||
|
||||
|
||||
def _stable_color(kind, index, label):
|
||||
key = f"{kind}:{index}:{label}".encode("utf-8", errors="replace")
|
||||
digest = hashlib.blake2b(key, digest_size=3).digest()
|
||||
return tuple(64 + channel % 192 for channel in digest)
|
||||
|
||||
|
||||
def _points(values, image_size):
|
||||
if not isinstance(values, (list, tuple)) or len(values) < 6:
|
||||
return []
|
||||
width, height = image_size
|
||||
points = []
|
||||
for index in range(0, len(values) - 1, 2):
|
||||
x, y = values[index], values[index + 1]
|
||||
if not isinstance(x, Real) or not isinstance(y, Real):
|
||||
return []
|
||||
if not math.isfinite(float(x)) or not math.isfinite(float(y)):
|
||||
return []
|
||||
points.append(
|
||||
(
|
||||
max(0, min(width - 1, round(float(x)))),
|
||||
max(0, min(height - 1, round(float(y)))),
|
||||
)
|
||||
)
|
||||
return points
|
||||
|
||||
|
||||
def _box(values, image_size):
|
||||
if not isinstance(values, (list, tuple)) or len(values) < 4:
|
||||
return None
|
||||
if not all(isinstance(value, Real) for value in values[:4]):
|
||||
return None
|
||||
coordinates = [float(value) for value in values[:4]]
|
||||
if not all(math.isfinite(value) for value in coordinates):
|
||||
return None
|
||||
x0, y0, x1, y1 = coordinates
|
||||
x0, x1 = sorted((x0, x1))
|
||||
y0, y1 = sorted((y0, y1))
|
||||
width, height = image_size
|
||||
x0 = max(0, min(width - 1, round(x0)))
|
||||
x1 = max(0, min(width - 1, round(x1)))
|
||||
y0 = max(0, min(height - 1, round(y0)))
|
||||
y1 = max(0, min(height - 1, round(y1)))
|
||||
if x1 <= x0 or y1 <= y0:
|
||||
return None
|
||||
return x0, y0, x1, y1
|
||||
|
||||
|
||||
def _polygon_list(group):
|
||||
if not isinstance(group, (list, tuple)) or not group:
|
||||
return []
|
||||
if isinstance(group[0], Real):
|
||||
return [group]
|
||||
return [item for item in group if isinstance(item, (list, tuple))]
|
||||
|
||||
|
||||
def _label_with_score(labels, scores, index):
|
||||
label = str(labels[index]) if index < len(labels) else ""
|
||||
if index < len(scores) and isinstance(scores[index], Real):
|
||||
score = f"{float(scores[index]):.3f}"
|
||||
return f"{label} {score}".strip()
|
||||
return label
|
||||
|
||||
|
||||
def _draw_label(draw, position, text, color, image_size):
|
||||
if not text:
|
||||
return
|
||||
x, y = position
|
||||
try:
|
||||
left, top, right, bottom = draw.textbbox((0, 0), text)
|
||||
text_width, text_height = right - left, bottom - top
|
||||
except AttributeError:
|
||||
text_width, text_height = draw.textlength(text), 11
|
||||
width, height = image_size
|
||||
x = max(0, min(width - text_width - 4, x))
|
||||
y = max(0, min(height - text_height - 4, y))
|
||||
background = (0, 0, 0) if sum(color) > 360 else (255, 255, 255)
|
||||
foreground = (255, 255, 255) if background == (0, 0, 0) else (0, 0, 0)
|
||||
draw.rectangle(
|
||||
(x, y, x + text_width + 4, y + text_height + 4),
|
||||
fill=background,
|
||||
)
|
||||
draw.text((x + 2, y + 2), text, fill=foreground)
|
||||
|
||||
|
||||
def _visualize(image, parsed):
|
||||
result = _spatial_result(parsed)
|
||||
mask = Image.new("L", image.size, 0)
|
||||
visual = image.copy().convert("RGB")
|
||||
mask_draw = ImageDraw.Draw(mask)
|
||||
draw = ImageDraw.Draw(visual)
|
||||
width = max(2, min(8, round(min(image.size) / 256 * 3)))
|
||||
labels = result.get("labels", [])
|
||||
scores = result.get("scores", [])
|
||||
|
||||
box_labels = result.get("bboxes_labels", labels)
|
||||
for index, values in enumerate(result.get("bboxes", [])):
|
||||
box = _box(values, image.size)
|
||||
if box is None:
|
||||
continue
|
||||
label = _label_with_score(box_labels, scores, index)
|
||||
color = _stable_color("box", index, label)
|
||||
mask_draw.rectangle(box, fill=255)
|
||||
draw.rectangle(box, outline=color, width=width)
|
||||
_draw_label(draw, (box[0], box[1]), label, color, image.size)
|
||||
|
||||
for index, values in enumerate(result.get("quad_boxes", [])):
|
||||
points = _points(values, image.size)
|
||||
if len(points) < 3:
|
||||
continue
|
||||
label = _label_with_score(labels, scores, index)
|
||||
color = _stable_color("quad", index, label)
|
||||
mask_draw.polygon(points, fill=255)
|
||||
draw.line(points + [points[0]], fill=color, width=width)
|
||||
_draw_label(draw, points[0], label, color, image.size)
|
||||
|
||||
polygon_labels = result.get("polygons_labels", labels)
|
||||
for index, group in enumerate(result.get("polygons", [])):
|
||||
label = _label_with_score(polygon_labels, scores, index)
|
||||
color = _stable_color("polygon", index, label)
|
||||
label_drawn = False
|
||||
for polygon in _polygon_list(group):
|
||||
points = _points(polygon, image.size)
|
||||
if len(points) < 3:
|
||||
continue
|
||||
mask_draw.polygon(points, fill=255)
|
||||
draw.line(points + [points[0]], fill=color, width=width)
|
||||
if not label_drawn:
|
||||
_draw_label(draw, points[0], label, color, image.size)
|
||||
label_drawn = True
|
||||
return mask, visual
|
||||
|
||||
|
||||
class Florence2(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"task": (list(TASKS),),
|
||||
"text_input": (
|
||||
"STRING",
|
||||
{
|
||||
"default": "",
|
||||
"multiline": True,
|
||||
"tooltip": (
|
||||
"Required only for phrase grounding, referring-expression "
|
||||
"segmentation, and open-vocabulary detection."
|
||||
),
|
||||
},
|
||||
),
|
||||
"model": (
|
||||
list(MODELS),
|
||||
{"default": "Florence-2 large FT (recommended)"},
|
||||
),
|
||||
"max_new_tokens": (
|
||||
"INT",
|
||||
{"default": 1024, "min": 1, "max": 4096},
|
||||
),
|
||||
"beams": ("INT", {"default": 3, "min": 1, "max": 8}),
|
||||
},
|
||||
"optional": {
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
"region": (
|
||||
"BOUNDING_BOX",
|
||||
{
|
||||
"tooltip": (
|
||||
"Core bounding box input required by Region to "
|
||||
"Segmentation/Category/Description/OCR."
|
||||
)
|
||||
},
|
||||
),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = ("STRING", "STRING", "MASK", "IMAGE")
|
||||
RETURN_NAMES = ("text", "structured_json", "mask", "visualization")
|
||||
FUNCTION = "run"
|
||||
CATEGORY = "VLM Nodes/Florence-2"
|
||||
|
||||
def run(
|
||||
self,
|
||||
image,
|
||||
task,
|
||||
text_input,
|
||||
model,
|
||||
max_new_tokens,
|
||||
beams,
|
||||
unload_after=False,
|
||||
region=None,
|
||||
):
|
||||
images = tensor_batch_to_pil(image)
|
||||
if not images:
|
||||
raise ValueError("Florence-2 requires at least one input image.")
|
||||
try:
|
||||
spec = TASKS[task]
|
||||
except KeyError as exc:
|
||||
raise ValueError(f"Unsupported Florence-2 task: {task}") from exc
|
||||
|
||||
extra_inputs = []
|
||||
for index, pil_image in enumerate(images):
|
||||
selected_region = _select_region(region, index, len(images))
|
||||
extra_inputs.append(
|
||||
_task_extra_input(
|
||||
task,
|
||||
text_input,
|
||||
selected_region,
|
||||
pil_image.size,
|
||||
)
|
||||
)
|
||||
|
||||
predictor = self.get_or_create_model(model, lambda: FlorencePredictor(model))
|
||||
texts, records, masks, visuals = [], [], [], []
|
||||
try:
|
||||
for pil_image, extra_input in zip(images, extra_inputs):
|
||||
raw, parsed = predictor.run(
|
||||
pil_image,
|
||||
spec.token,
|
||||
extra_input,
|
||||
max_new_tokens,
|
||||
beams,
|
||||
)
|
||||
texts.append(_clean_decoded_text(raw))
|
||||
records.append(parsed)
|
||||
mask, visual = _visualize(pil_image, parsed)
|
||||
masks.append(pil_mask_to_tensor(mask))
|
||||
visuals.append(pil_to_tensor(visual))
|
||||
return (
|
||||
batch_text(texts),
|
||||
json.dumps(
|
||||
records,
|
||||
ensure_ascii=False,
|
||||
default=_json_default,
|
||||
sort_keys=True,
|
||||
),
|
||||
torch.cat(masks),
|
||||
torch.cat(visuals),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {"Florence2": Florence2}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {"Florence2": "Florence-2 Multitask Vision"}
|
||||
@@ -0,0 +1,413 @@
|
||||
"""Dependency-light geometry, mask, color, and association primitives."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import colorsys
|
||||
import hashlib
|
||||
import math
|
||||
from collections.abc import Iterable, Mapping
|
||||
from dataclasses import dataclass
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import Image, ImageDraw
|
||||
|
||||
from .vision_types import BoxXYXY, Detection, PointXY, Polygon
|
||||
|
||||
|
||||
def _dimensions(width: int, height: int) -> tuple[int, int]:
|
||||
if not isinstance(width, int) or width <= 0:
|
||||
raise ValueError("width must be a positive integer.")
|
||||
if not isinstance(height, int) or height <= 0:
|
||||
raise ValueError("height must be a positive integer.")
|
||||
return width, height
|
||||
|
||||
|
||||
def _ordered_box(box: Iterable[float]) -> BoxXYXY:
|
||||
values = tuple(float(value) for value in box)
|
||||
if len(values) != 4 or not all(math.isfinite(value) for value in values):
|
||||
raise ValueError("A box must contain four finite xyxy values.")
|
||||
x1, y1, x2, y2 = values
|
||||
if x2 < x1 or y2 < y1:
|
||||
raise ValueError("A box must satisfy x2 >= x1 and y2 >= y1.")
|
||||
return x1, y1, x2, y2
|
||||
|
||||
|
||||
def clip_box(box: Iterable[float], width: int, height: int) -> BoxXYXY:
|
||||
"""Clamp a pixel xyxy box to an image, preserving exclusive x2/y2."""
|
||||
|
||||
width, height = _dimensions(width, height)
|
||||
x1, y1, x2, y2 = _ordered_box(box)
|
||||
return (
|
||||
min(max(x1, 0.0), float(width)),
|
||||
min(max(y1, 0.0), float(height)),
|
||||
min(max(x2, 0.0), float(width)),
|
||||
min(max(y2, 0.0), float(height)),
|
||||
)
|
||||
|
||||
|
||||
def clip_polygon(
|
||||
polygon: Iterable[Iterable[float]],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> Polygon:
|
||||
width, height = _dimensions(width, height)
|
||||
points = []
|
||||
for point in polygon:
|
||||
values = tuple(float(value) for value in point)
|
||||
if len(values) != 2 or not all(math.isfinite(value) for value in values):
|
||||
raise ValueError("Polygon points must contain two finite values.")
|
||||
points.append(
|
||||
(
|
||||
min(max(values[0], 0.0), float(width)),
|
||||
min(max(values[1], 0.0), float(height)),
|
||||
)
|
||||
)
|
||||
if len(points) < 3:
|
||||
raise ValueError("A polygon requires at least three points.")
|
||||
return tuple(points)
|
||||
|
||||
|
||||
def normalize_box(
|
||||
box: Iterable[float],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> BoxXYXY:
|
||||
width, height = _dimensions(width, height)
|
||||
x1, y1, x2, y2 = clip_box(box, width, height)
|
||||
return x1 / width, y1 / height, x2 / width, y2 / height
|
||||
|
||||
|
||||
def denormalize_box(
|
||||
box: Iterable[float],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> BoxXYXY:
|
||||
width, height = _dimensions(width, height)
|
||||
x1, y1, x2, y2 = _ordered_box(box)
|
||||
if any(value < 0.0 or value > 1.0 for value in (x1, y1, x2, y2)):
|
||||
raise ValueError("Normalized box coordinates must be between 0 and 1.")
|
||||
return x1 * width, y1 * height, x2 * width, y2 * height
|
||||
|
||||
|
||||
def box_area(box: Iterable[float]) -> float:
|
||||
x1, y1, x2, y2 = _ordered_box(box)
|
||||
return (x2 - x1) * (y2 - y1)
|
||||
|
||||
|
||||
def box_center(box: Iterable[float]) -> PointXY:
|
||||
x1, y1, x2, y2 = _ordered_box(box)
|
||||
return (x1 + x2) * 0.5, (y1 + y2) * 0.5
|
||||
|
||||
|
||||
def polygon_area(polygon: Iterable[Iterable[float]]) -> float:
|
||||
points = [tuple(float(value) for value in point) for point in polygon]
|
||||
if len(points) < 3 or any(len(point) != 2 for point in points):
|
||||
raise ValueError("A polygon requires at least three xy points.")
|
||||
if any(not math.isfinite(value) for point in points for value in point):
|
||||
raise ValueError("Polygon coordinates must be finite.")
|
||||
twice_area = sum(
|
||||
x1 * y2 - x2 * y1 for (x1, y1), (x2, y2) in zip(points, points[1:] + points[:1])
|
||||
)
|
||||
return abs(twice_area) * 0.5
|
||||
|
||||
|
||||
def bbox_iou(first: Iterable[float], second: Iterable[float]) -> float:
|
||||
ax1, ay1, ax2, ay2 = _ordered_box(first)
|
||||
bx1, by1, bx2, by2 = _ordered_box(second)
|
||||
intersection = max(0.0, min(ax2, bx2) - max(ax1, bx1)) * max(
|
||||
0.0, min(ay2, by2) - max(ay1, by1)
|
||||
)
|
||||
union = box_area(first) + box_area(second) - intersection
|
||||
return intersection / union if union > 0 else 0.0
|
||||
|
||||
|
||||
def mask_iou(
|
||||
first: torch.Tensor | np.ndarray,
|
||||
second: torch.Tensor | np.ndarray,
|
||||
*,
|
||||
threshold: float = 0.5,
|
||||
) -> float:
|
||||
first_tensor = torch.as_tensor(first)
|
||||
second_tensor = torch.as_tensor(second)
|
||||
if first_tensor.ndim != 2 or second_tensor.ndim != 2:
|
||||
raise ValueError("Masks must have shape [height, width].")
|
||||
if first_tensor.shape != second_tensor.shape:
|
||||
raise ValueError("Masks must have the same shape.")
|
||||
first_bool = first_tensor > float(threshold)
|
||||
second_bool = second_tensor > float(threshold)
|
||||
intersection = torch.logical_and(first_bool, second_bool).sum().item()
|
||||
union = torch.logical_or(first_bool, second_bool).sum().item()
|
||||
return float(intersection / union) if union else 0.0
|
||||
|
||||
|
||||
def deterministic_color(value: object) -> tuple[int, int, int]:
|
||||
"""Return a readable RGB color that is stable across Python processes."""
|
||||
|
||||
digest = hashlib.sha256(str(value).encode("utf-8")).digest()
|
||||
hue = int.from_bytes(digest[:2], "big") / 65535.0
|
||||
saturation = 0.62 + digest[2] / 255.0 * 0.22
|
||||
brightness = 0.78 + digest[3] / 255.0 * 0.17
|
||||
return tuple(
|
||||
round(channel * 255)
|
||||
for channel in colorsys.hsv_to_rgb(hue, saturation, brightness)
|
||||
)
|
||||
|
||||
|
||||
def box_to_mask(
|
||||
box: Iterable[float],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> torch.Tensor:
|
||||
width, height = _dimensions(width, height)
|
||||
x1, y1, x2, y2 = clip_box(box, width, height)
|
||||
left = max(0, min(width, math.floor(x1)))
|
||||
top = max(0, min(height, math.floor(y1)))
|
||||
right = max(left, min(width, math.ceil(x2)))
|
||||
bottom = max(top, min(height, math.ceil(y2)))
|
||||
mask = torch.zeros((height, width), dtype=torch.float32)
|
||||
mask[top:bottom, left:right] = 1.0
|
||||
return mask
|
||||
|
||||
|
||||
def polygon_to_mask(
|
||||
polygon: Iterable[Iterable[float]],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> torch.Tensor:
|
||||
width, height = _dimensions(width, height)
|
||||
points = clip_polygon(polygon, width, height)
|
||||
canvas = Image.new("L", (width, height), 0)
|
||||
ImageDraw.Draw(canvas).polygon(points, fill=255)
|
||||
array = np.asarray(canvas, dtype=np.float32) / 255.0
|
||||
return torch.from_numpy(array.copy())
|
||||
|
||||
|
||||
def quad_to_mask(
|
||||
quad: Iterable[Iterable[float]],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> torch.Tensor:
|
||||
points = tuple(tuple(point) for point in quad)
|
||||
if len(points) != 4:
|
||||
raise ValueError("A quad must contain exactly four points.")
|
||||
return polygon_to_mask(points, width, height)
|
||||
|
||||
|
||||
def detection_to_mask(
|
||||
detection: Detection,
|
||||
width: int,
|
||||
height: int,
|
||||
) -> torch.Tensor:
|
||||
"""Rasterize the most precise geometry available on a detection."""
|
||||
|
||||
width, height = _dimensions(width, height)
|
||||
if not isinstance(detection, Detection):
|
||||
raise TypeError("detection must be a Detection.")
|
||||
if detection.mask is not None:
|
||||
if tuple(detection.mask.shape) != (height, width):
|
||||
raise ValueError("Detection mask shape does not match the image.")
|
||||
return detection.mask.detach().to(dtype=torch.float32).clamp(0, 1).clone()
|
||||
if detection.polygon is not None:
|
||||
return polygon_to_mask(detection.polygon, width, height)
|
||||
if detection.quad is not None:
|
||||
return quad_to_mask(detection.quad, width, height)
|
||||
return box_to_mask(detection.bbox_xyxy, width, height)
|
||||
|
||||
|
||||
def individual_detection_masks(
|
||||
detections: Iterable[Detection],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> torch.Tensor:
|
||||
width, height = _dimensions(width, height)
|
||||
masks = [detection_to_mask(detection, width, height) for detection in detections]
|
||||
if not masks:
|
||||
return torch.zeros((0, height, width), dtype=torch.float32)
|
||||
return torch.stack(masks).to(dtype=torch.float32)
|
||||
|
||||
|
||||
def union_detection_mask(
|
||||
detections: Iterable[Detection],
|
||||
width: int,
|
||||
height: int,
|
||||
) -> torch.Tensor:
|
||||
masks = individual_detection_masks(detections, width, height)
|
||||
if masks.shape[0] == 0:
|
||||
return torch.zeros((height, width), dtype=torch.float32)
|
||||
return masks.amax(dim=0).clamp(0, 1)
|
||||
|
||||
|
||||
def bbox_from_mask(
|
||||
mask: torch.Tensor | np.ndarray,
|
||||
*,
|
||||
threshold: float = 0.5,
|
||||
) -> BoxXYXY | None:
|
||||
value = torch.as_tensor(mask)
|
||||
if value.ndim != 2:
|
||||
raise ValueError("mask must have shape [height, width].")
|
||||
locations = torch.nonzero(value > float(threshold), as_tuple=False)
|
||||
if locations.numel() == 0:
|
||||
return None
|
||||
y1, x1 = locations.amin(dim=0).tolist()
|
||||
y2, x2 = locations.amax(dim=0).tolist()
|
||||
return float(x1), float(y1), float(x2 + 1), float(y2 + 1)
|
||||
|
||||
|
||||
def translate_box(
|
||||
box: Iterable[float],
|
||||
dx: float,
|
||||
dy: float,
|
||||
) -> BoxXYXY:
|
||||
x1, y1, x2, y2 = _ordered_box(box)
|
||||
dx = float(dx)
|
||||
dy = float(dy)
|
||||
if not math.isfinite(dx) or not math.isfinite(dy):
|
||||
raise ValueError("Box motion must be finite.")
|
||||
return x1 + dx, y1 + dy, x2 + dx, y2 + dy
|
||||
|
||||
|
||||
def expand_box(
|
||||
box: Iterable[float],
|
||||
width: int,
|
||||
height: int,
|
||||
*,
|
||||
padding: float = 0.0,
|
||||
square: bool = False,
|
||||
) -> BoxXYXY:
|
||||
"""Pad and optionally square a box around its center, then clip it."""
|
||||
|
||||
width, height = _dimensions(width, height)
|
||||
if not math.isfinite(float(padding)) or padding < 0:
|
||||
raise ValueError("padding must be finite and non-negative.")
|
||||
x1, y1, x2, y2 = _ordered_box(box)
|
||||
x1 -= padding
|
||||
y1 -= padding
|
||||
x2 += padding
|
||||
y2 += padding
|
||||
if square:
|
||||
center_x, center_y = (x1 + x2) * 0.5, (y1 + y2) * 0.5
|
||||
half = max(x2 - x1, y2 - y1) * 0.5
|
||||
x1, y1, x2, y2 = (
|
||||
center_x - half,
|
||||
center_y - half,
|
||||
center_x + half,
|
||||
center_y + half,
|
||||
)
|
||||
side = x2 - x1
|
||||
if side <= width:
|
||||
if x1 < 0:
|
||||
x2 -= x1
|
||||
x1 = 0.0
|
||||
elif x2 > width:
|
||||
x1 -= x2 - width
|
||||
x2 = float(width)
|
||||
if side <= height:
|
||||
if y1 < 0:
|
||||
y2 -= y1
|
||||
y1 = 0.0
|
||||
elif y2 > height:
|
||||
y1 -= y2 - height
|
||||
y2 = float(height)
|
||||
return clip_box((x1, y1, x2, y2), width, height)
|
||||
|
||||
|
||||
@dataclass(frozen=True, slots=True)
|
||||
class AssociationResult:
|
||||
"""Stable one-to-one detection assignment by descending overlap."""
|
||||
|
||||
matches: tuple[tuple[int, int, float], ...]
|
||||
unmatched_previous: tuple[int, ...]
|
||||
unmatched_current: tuple[int, ...]
|
||||
|
||||
|
||||
def associate_detections(
|
||||
previous: Iterable[Detection],
|
||||
current: Iterable[Detection],
|
||||
*,
|
||||
minimum_iou: float = 0.3,
|
||||
label_aware: bool = True,
|
||||
motion_by_track: Mapping[int, tuple[float, float]] | None = None,
|
||||
) -> AssociationResult:
|
||||
"""Associate detections without SciPy or backend-specific operators.
|
||||
|
||||
Candidates are greedily selected by descending IoU with deterministic
|
||||
index tie-breaks. Optional per-track motion offsets predict the previous
|
||||
box before overlap is measured.
|
||||
"""
|
||||
|
||||
previous_items = tuple(previous)
|
||||
current_items = tuple(current)
|
||||
if not 0.0 <= float(minimum_iou) <= 1.0:
|
||||
raise ValueError("minimum_iou must be between 0 and 1.")
|
||||
if any(not isinstance(item, Detection) for item in previous_items):
|
||||
raise TypeError("previous must contain Detection values.")
|
||||
if any(not isinstance(item, Detection) for item in current_items):
|
||||
raise TypeError("current must contain Detection values.")
|
||||
|
||||
candidates = []
|
||||
for previous_index, old in enumerate(previous_items):
|
||||
old_box = old.bbox_xyxy
|
||||
if old.track_id is not None and motion_by_track:
|
||||
motion = motion_by_track.get(old.track_id)
|
||||
if motion is not None:
|
||||
old_box = translate_box(old_box, motion[0], motion[1])
|
||||
for current_index, new in enumerate(current_items):
|
||||
if (
|
||||
label_aware
|
||||
and old.label is not None
|
||||
and new.label is not None
|
||||
and " ".join(old.label.casefold().split())
|
||||
!= " ".join(new.label.casefold().split())
|
||||
):
|
||||
continue
|
||||
overlap = bbox_iou(old_box, new.bbox_xyxy)
|
||||
if overlap >= float(minimum_iou):
|
||||
candidates.append((-overlap, previous_index, current_index, overlap))
|
||||
|
||||
matched_previous: set[int] = set()
|
||||
matched_current: set[int] = set()
|
||||
matches = []
|
||||
for _negative, previous_index, current_index, overlap in sorted(candidates):
|
||||
if previous_index in matched_previous or current_index in matched_current:
|
||||
continue
|
||||
matched_previous.add(previous_index)
|
||||
matched_current.add(current_index)
|
||||
matches.append((previous_index, current_index, overlap))
|
||||
|
||||
return AssociationResult(
|
||||
matches=tuple(matches),
|
||||
unmatched_previous=tuple(
|
||||
index
|
||||
for index in range(len(previous_items))
|
||||
if index not in matched_previous
|
||||
),
|
||||
unmatched_current=tuple(
|
||||
index for index in range(len(current_items)) if index not in matched_current
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
__all__ = [
|
||||
"AssociationResult",
|
||||
"associate_detections",
|
||||
"bbox_from_mask",
|
||||
"bbox_iou",
|
||||
"box_area",
|
||||
"box_center",
|
||||
"box_to_mask",
|
||||
"clip_box",
|
||||
"clip_polygon",
|
||||
"denormalize_box",
|
||||
"detection_to_mask",
|
||||
"deterministic_color",
|
||||
"expand_box",
|
||||
"individual_detection_masks",
|
||||
"mask_iou",
|
||||
"normalize_box",
|
||||
"polygon_area",
|
||||
"polygon_to_mask",
|
||||
"quad_to_mask",
|
||||
"translate_box",
|
||||
"union_detection_mask",
|
||||
]
|
||||
@@ -0,0 +1,537 @@
|
||||
"""Fast open-vocabulary object detection with maintained Transformers models.
|
||||
|
||||
The node deliberately presents one stable ComfyUI interface while keeping
|
||||
model-specific preprocessing and postprocessing behind a small adapter. Model
|
||||
downloads are lazy, inference participates in ComfyUI's VRAM management, and
|
||||
all spatial output uses the pack's versioned pixel-coordinate contract.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import math
|
||||
from dataclasses import dataclass
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
from PIL import ImageDraw
|
||||
|
||||
from .geometry import deterministic_color
|
||||
from .runtime import (
|
||||
CachedModelNode,
|
||||
ManagedTorchModel,
|
||||
inference_context,
|
||||
model_device,
|
||||
move_inputs,
|
||||
require_module,
|
||||
snapshot_download,
|
||||
tensor_batch_to_pil,
|
||||
torch_dtype,
|
||||
)
|
||||
from .vision_types import (
|
||||
VLM_DETECTIONS,
|
||||
Detection,
|
||||
DetectionSequence,
|
||||
FrameDetections,
|
||||
)
|
||||
|
||||
|
||||
@dataclass(frozen=True)
|
||||
class DetectorSpec:
|
||||
model_id: str
|
||||
cache_name: str
|
||||
family: str
|
||||
description: str
|
||||
|
||||
|
||||
MODEL_SPECS = {
|
||||
"Grounding DINO Tiny (fast)": DetectorSpec(
|
||||
"IDEA-Research/grounding-dino-tiny",
|
||||
"grounding-dino-tiny",
|
||||
"grounding_dino",
|
||||
"Fast, accurate open-vocabulary grounding.",
|
||||
),
|
||||
"Grounding DINO Base": DetectorSpec(
|
||||
"IDEA-Research/grounding-dino-base",
|
||||
"grounding-dino-base",
|
||||
"grounding_dino",
|
||||
"Higher-quality open-vocabulary grounding.",
|
||||
),
|
||||
"OWLv2 Base Ensemble": DetectorSpec(
|
||||
"google/owlv2-base-patch16-ensemble",
|
||||
"owlv2-base-patch16-ensemble",
|
||||
"owlv2",
|
||||
"Strong zero-shot detector for lists of visual concepts.",
|
||||
),
|
||||
"OmDet Turbo Swin Tiny (fast)": DetectorSpec(
|
||||
"omlab/omdet-turbo-swin-tiny-hf",
|
||||
"omdet-turbo-swin-tiny",
|
||||
"omdet",
|
||||
"Efficient real-time-oriented open-vocabulary detector.",
|
||||
),
|
||||
}
|
||||
|
||||
|
||||
def parse_labels(value: str) -> list[str]:
|
||||
"""Parse user concepts without splitting meaningful multi-word labels."""
|
||||
|
||||
labels: list[str] = []
|
||||
for line in str(value or "").replace(";", "\n").splitlines():
|
||||
for candidate in line.split(","):
|
||||
label = " ".join(candidate.strip().split())
|
||||
if label and label not in labels:
|
||||
labels.append(label)
|
||||
if not labels:
|
||||
raise ValueError("Enter at least one object label or referring phrase.")
|
||||
return labels
|
||||
|
||||
|
||||
def _safe_score(value: Any) -> float:
|
||||
score = float(value.item() if hasattr(value, "item") else value)
|
||||
return min(1.0, max(0.0, score))
|
||||
|
||||
|
||||
def _result_labels(result: dict[str, Any], labels: list[str]) -> list[str]:
|
||||
text_labels = result.get("text_labels")
|
||||
if text_labels is not None:
|
||||
return [str(label) for label in text_labels]
|
||||
|
||||
raw_labels = result.get("labels", result.get("classes", []))
|
||||
resolved = []
|
||||
for value in raw_labels:
|
||||
if isinstance(value, str):
|
||||
resolved.append(value)
|
||||
continue
|
||||
index = int(value.item() if hasattr(value, "item") else value)
|
||||
resolved.append(labels[index] if 0 <= index < len(labels) else str(index))
|
||||
return resolved
|
||||
|
||||
|
||||
def result_to_detections(
|
||||
result: dict[str, Any],
|
||||
*,
|
||||
labels: list[str],
|
||||
width: int,
|
||||
height: int,
|
||||
frame_index: int,
|
||||
timestamp: float,
|
||||
source: str,
|
||||
max_detections: int,
|
||||
) -> tuple[Detection, ...]:
|
||||
"""Normalize a Transformers detector result into immutable detections."""
|
||||
|
||||
boxes = result.get("boxes", ())
|
||||
scores = result.get("scores", ())
|
||||
resolved_labels = _result_labels(result, labels)
|
||||
count = min(len(boxes), len(scores), len(resolved_labels))
|
||||
records = []
|
||||
for index in range(count):
|
||||
box_value = boxes[index]
|
||||
if hasattr(box_value, "detach"):
|
||||
box_value = box_value.detach().to(device="cpu").tolist()
|
||||
x1, y1, x2, y2 = (float(value) for value in box_value)
|
||||
x1 = min(float(width), max(0.0, x1))
|
||||
y1 = min(float(height), max(0.0, y1))
|
||||
x2 = min(float(width), max(x1, x2))
|
||||
y2 = min(float(height), max(y1, y2))
|
||||
if x2 <= x1 or y2 <= y1:
|
||||
continue
|
||||
records.append(
|
||||
Detection(
|
||||
bbox_xyxy=(x1, y1, x2, y2),
|
||||
label=resolved_labels[index].strip() or None,
|
||||
score=_safe_score(scores[index]),
|
||||
frame_index=frame_index,
|
||||
timestamp=timestamp,
|
||||
source=source,
|
||||
metadata={"model_id": source},
|
||||
)
|
||||
)
|
||||
records.sort(
|
||||
key=lambda item: (
|
||||
-(item.score or 0.0),
|
||||
item.label or "",
|
||||
item.bbox_xyxy,
|
||||
)
|
||||
)
|
||||
return tuple(records[:max_detections])
|
||||
|
||||
|
||||
def _post_process(
|
||||
processor: Any,
|
||||
spec: DetectorSpec,
|
||||
outputs: Any,
|
||||
inputs: dict[str, Any],
|
||||
labels: list[str],
|
||||
sizes: list[tuple[int, int]],
|
||||
box_threshold: float,
|
||||
text_threshold: float,
|
||||
nms_threshold: float,
|
||||
max_detections: int,
|
||||
) -> list[dict[str, Any]]:
|
||||
if spec.family == "grounding_dino":
|
||||
kwargs = {
|
||||
"threshold": float(box_threshold),
|
||||
"text_threshold": float(text_threshold),
|
||||
"target_sizes": sizes,
|
||||
}
|
||||
input_ids = inputs.get("input_ids")
|
||||
if input_ids is not None:
|
||||
kwargs["input_ids"] = input_ids
|
||||
return processor.post_process_grounded_object_detection(outputs, **kwargs)
|
||||
if spec.family == "omdet":
|
||||
return processor.post_process_grounded_object_detection(
|
||||
outputs,
|
||||
text_labels=[labels] * len(sizes),
|
||||
threshold=float(box_threshold),
|
||||
nms_threshold=float(nms_threshold),
|
||||
target_sizes=sizes,
|
||||
max_num_det=int(max_detections),
|
||||
)
|
||||
return processor.post_process_grounded_object_detection(
|
||||
outputs,
|
||||
threshold=float(box_threshold),
|
||||
target_sizes=sizes,
|
||||
text_labels=[labels] * len(sizes),
|
||||
)
|
||||
|
||||
|
||||
class OpenVocabularyDetector:
|
||||
def __init__(self, spec: DetectorSpec, precision: str = "auto"):
|
||||
transformers = require_module("transformers")
|
||||
model_path = snapshot_download(
|
||||
spec.model_id,
|
||||
spec.cache_name,
|
||||
ignore_patterns=["*.bin", "*.gguf", "*.onnx", "*.tflite"],
|
||||
)
|
||||
processor = transformers.AutoProcessor.from_pretrained(model_path)
|
||||
model_class = transformers.AutoModelForZeroShotObjectDetection
|
||||
dtype = torch_dtype(precision)
|
||||
# Transformers 4.x consumes ``torch_dtype``; 5.x renamed it to
|
||||
# ``dtype``. Passing the 5.x name to 4.x leaks into the model
|
||||
# constructor and crashes Grounding DINO at runtime.
|
||||
major = int(str(transformers.__version__).split(".", 1)[0])
|
||||
dtype_kwargs = {"dtype": dtype} if major >= 5 else {"torch_dtype": dtype}
|
||||
model = model_class.from_pretrained(model_path, **dtype_kwargs)
|
||||
model.eval()
|
||||
self.spec = spec
|
||||
self.dtype = dtype
|
||||
self.processor = processor
|
||||
self.handle = ManagedTorchModel(model, processor=processor)
|
||||
|
||||
def close(self):
|
||||
self.handle.close()
|
||||
|
||||
def detect(
|
||||
self,
|
||||
images: torch.Tensor,
|
||||
labels: list[str],
|
||||
*,
|
||||
box_threshold: float,
|
||||
text_threshold: float,
|
||||
nms_threshold: float,
|
||||
max_detections: int,
|
||||
fps: float,
|
||||
batch_size: int,
|
||||
) -> DetectionSequence:
|
||||
if not math.isfinite(fps) or fps <= 0:
|
||||
raise ValueError("fps must be finite and positive.")
|
||||
if not isinstance(batch_size, int) or batch_size < 1:
|
||||
raise ValueError("batch_size must be a positive integer.")
|
||||
frames = []
|
||||
pil_images = tensor_batch_to_pil(images)
|
||||
model = self.handle.ensure_loaded()
|
||||
device = model_device(model)
|
||||
for start in range(0, len(pil_images), batch_size):
|
||||
image_batch = pil_images[start : start + batch_size]
|
||||
text = [labels] * len(image_batch)
|
||||
inputs = self.processor(
|
||||
images=image_batch,
|
||||
text=text,
|
||||
return_tensors="pt",
|
||||
)
|
||||
inputs = move_inputs(inputs, device, floating_dtype=self.dtype)
|
||||
with torch.inference_mode(), inference_context(device, self.dtype):
|
||||
outputs = model(**inputs)
|
||||
results = _post_process(
|
||||
self.processor,
|
||||
self.spec,
|
||||
outputs,
|
||||
inputs,
|
||||
labels,
|
||||
[(image.height, image.width) for image in image_batch],
|
||||
box_threshold,
|
||||
text_threshold,
|
||||
nms_threshold,
|
||||
max_detections,
|
||||
)
|
||||
if len(results) != len(image_batch):
|
||||
raise RuntimeError(
|
||||
f"{self.spec.model_id} returned {len(results)} result sets "
|
||||
f"for a batch of {len(image_batch)} images."
|
||||
)
|
||||
for offset, (image, result) in enumerate(
|
||||
zip(image_batch, results, strict=True)
|
||||
):
|
||||
frame_index = start + offset
|
||||
detections = result_to_detections(
|
||||
result,
|
||||
labels=labels,
|
||||
width=image.width,
|
||||
height=image.height,
|
||||
frame_index=frame_index,
|
||||
timestamp=frame_index / fps,
|
||||
source=self.spec.model_id,
|
||||
max_detections=max_detections,
|
||||
)
|
||||
frames.append(
|
||||
FrameDetections(
|
||||
frame_index=frame_index,
|
||||
timestamp=frame_index / fps,
|
||||
width=image.width,
|
||||
height=image.height,
|
||||
detections=detections,
|
||||
)
|
||||
)
|
||||
first = pil_images[0]
|
||||
return DetectionSequence(
|
||||
width=first.width,
|
||||
height=first.height,
|
||||
frames=tuple(frames),
|
||||
frame_count=len(frames),
|
||||
fps=fps,
|
||||
source=self.spec.model_id,
|
||||
metadata={"labels": labels, "model_family": self.spec.family},
|
||||
)
|
||||
|
||||
|
||||
def render_detections(
|
||||
images: torch.Tensor, detections: DetectionSequence
|
||||
) -> torch.Tensor:
|
||||
rendered = []
|
||||
for index, image in enumerate(tensor_batch_to_pil(images)):
|
||||
canvas = image.copy()
|
||||
draw = ImageDraw.Draw(canvas)
|
||||
frame = detections.frame(index)
|
||||
for detection in frame.detections if frame else ():
|
||||
color = deterministic_color(
|
||||
detection.track_id
|
||||
if detection.track_id is not None
|
||||
else detection.label or "object"
|
||||
)
|
||||
color = tuple(int(component) for component in color)
|
||||
x1, y1, x2, y2 = detection.bbox_xyxy
|
||||
draw.rectangle(
|
||||
(x1, y1, max(x1, x2 - 1), max(y1, y2 - 1)),
|
||||
outline=color,
|
||||
width=max(2, round(min(image.size) / 256)),
|
||||
)
|
||||
label = detection.label or "object"
|
||||
if detection.score is not None:
|
||||
label += f" {detection.score:.2f}"
|
||||
text_box = draw.textbbox((x1, y1), label)
|
||||
draw.rectangle(text_box, fill=color)
|
||||
draw.text((x1, y1), label, fill=(0, 0, 0))
|
||||
array = torch.from_numpy(np.asarray(canvas, dtype=np.float32).copy())
|
||||
rendered.append(array / 255.0)
|
||||
return torch.stack(rendered)
|
||||
|
||||
|
||||
def detection_box_masks(
|
||||
detections: DetectionSequence,
|
||||
) -> torch.Tensor:
|
||||
masks = torch.zeros(
|
||||
(detections.frame_count, detections.height, detections.width),
|
||||
dtype=torch.float32,
|
||||
)
|
||||
for frame in detections.frames:
|
||||
for detection in frame.detections:
|
||||
x1, y1, x2, y2 = detection.bbox_xyxy
|
||||
ix1, iy1 = int(x1), int(y1)
|
||||
ix2, iy2 = int(math.ceil(x2)), int(math.ceil(y2))
|
||||
masks[frame.frame_index, iy1:iy2, ix1:ix2] = 1.0
|
||||
return masks
|
||||
|
||||
|
||||
def _core_box(detection: Detection) -> dict[str, Any]:
|
||||
x1, y1, x2, y2 = detection.bbox_xyxy
|
||||
left, top = math.floor(x1), math.floor(y1)
|
||||
right, bottom = math.ceil(x2), math.ceil(y2)
|
||||
return {
|
||||
"x": left,
|
||||
"y": top,
|
||||
"width": right - left,
|
||||
"height": bottom - top,
|
||||
"label": detection.label,
|
||||
"score": detection.score,
|
||||
"metadata": {
|
||||
"frame_index": detection.frame_index,
|
||||
"label": detection.label,
|
||||
"score": detection.score,
|
||||
"source": detection.source,
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
def core_bounding_box_frames(
|
||||
detections: DetectionSequence,
|
||||
) -> list[list[dict[str, Any]]]:
|
||||
"""Return the nested per-frame convention used by core BOUNDING_BOX."""
|
||||
|
||||
frames = [[] for _index in range(detections.frame_count)]
|
||||
for frame in detections.frames:
|
||||
frames[frame.frame_index] = [
|
||||
_core_box(detection) for detection in frame.detections
|
||||
]
|
||||
return frames
|
||||
|
||||
|
||||
def core_bounding_boxes(detections: DetectionSequence) -> list[dict[str, Any]]:
|
||||
"""Return the flat metadata-rich BOUNDING_BOXES contract."""
|
||||
|
||||
result = []
|
||||
for frame in detections.frames:
|
||||
for detection in frame.detections:
|
||||
result.append(_core_box(detection))
|
||||
return result
|
||||
|
||||
|
||||
class VLMOpenVocabularyDetection(CachedModelNode):
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"image": ("IMAGE",),
|
||||
"model": (tuple(MODEL_SPECS),),
|
||||
"labels": (
|
||||
"STRING",
|
||||
{
|
||||
"multiline": True,
|
||||
"default": "person, animal, vehicle",
|
||||
"tooltip": "Comma, semicolon, or newline-separated concepts.",
|
||||
},
|
||||
),
|
||||
"box_threshold": (
|
||||
"FLOAT",
|
||||
{"default": 0.3, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"text_threshold": (
|
||||
"FLOAT",
|
||||
{"default": 0.25, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"max_detections": (
|
||||
"INT",
|
||||
{"default": 100, "min": 1, "max": 1000},
|
||||
),
|
||||
"fps": (
|
||||
"FLOAT",
|
||||
{
|
||||
"default": 1.0,
|
||||
"min": 0.001,
|
||||
"max": 1000.0,
|
||||
"step": 0.001,
|
||||
"tooltip": (
|
||||
"Connect Get Video Components fps for video batches."
|
||||
),
|
||||
},
|
||||
),
|
||||
},
|
||||
"optional": {
|
||||
"nms_threshold": (
|
||||
"FLOAT",
|
||||
{"default": 0.5, "min": 0.0, "max": 1.0, "step": 0.01},
|
||||
),
|
||||
"precision": (("auto", "bfloat16", "float16", "float32"),),
|
||||
"batch_size": (
|
||||
"INT",
|
||||
{
|
||||
"default": 1,
|
||||
"min": 1,
|
||||
"max": 16,
|
||||
"tooltip": (
|
||||
"Frames per model call. Increase only when VRAM allows."
|
||||
),
|
||||
},
|
||||
),
|
||||
"unload_after": ("BOOLEAN", {"default": False}),
|
||||
},
|
||||
}
|
||||
|
||||
RETURN_TYPES = (
|
||||
VLM_DETECTIONS,
|
||||
"STRING",
|
||||
"IMAGE",
|
||||
"MASK",
|
||||
"BOUNDING_BOX",
|
||||
"BOUNDING_BOXES",
|
||||
)
|
||||
RETURN_NAMES = (
|
||||
"detections",
|
||||
"json",
|
||||
"preview",
|
||||
"box_mask",
|
||||
"bounding_boxes",
|
||||
"bounding_boxes_with_metadata",
|
||||
)
|
||||
FUNCTION = "detect"
|
||||
CATEGORY = "VLM Nodes/Vision/Detection"
|
||||
DESCRIPTION = (
|
||||
"Detect text-specified objects with one portable interface. Outputs "
|
||||
"versioned detections, JSON, preview, box masks, and core boxes."
|
||||
)
|
||||
|
||||
def detect(
|
||||
self,
|
||||
image,
|
||||
model,
|
||||
labels,
|
||||
box_threshold,
|
||||
text_threshold,
|
||||
max_detections,
|
||||
fps,
|
||||
nms_threshold=0.5,
|
||||
precision="auto",
|
||||
batch_size=1,
|
||||
unload_after=False,
|
||||
):
|
||||
concepts = parse_labels(labels)
|
||||
fps_value = float(fps)
|
||||
batch_size_value = int(batch_size)
|
||||
if not math.isfinite(fps_value) or fps_value <= 0:
|
||||
raise ValueError("fps must be finite and positive.")
|
||||
if batch_size_value < 1:
|
||||
raise ValueError("batch_size must be a positive integer.")
|
||||
spec = MODEL_SPECS[model]
|
||||
predictor = self.get_or_create_model(
|
||||
(spec.model_id, precision),
|
||||
lambda: OpenVocabularyDetector(spec, precision),
|
||||
)
|
||||
try:
|
||||
detections = predictor.detect(
|
||||
image,
|
||||
concepts,
|
||||
box_threshold=box_threshold,
|
||||
text_threshold=text_threshold,
|
||||
nms_threshold=nms_threshold,
|
||||
max_detections=max_detections,
|
||||
fps=fps_value,
|
||||
batch_size=batch_size_value,
|
||||
)
|
||||
return (
|
||||
detections,
|
||||
detections.to_json(indent=2),
|
||||
render_detections(image, detections),
|
||||
detection_box_masks(detections),
|
||||
core_bounding_box_frames(detections),
|
||||
core_bounding_boxes(detections),
|
||||
)
|
||||
finally:
|
||||
self.maybe_clear_model(unload_after)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {
|
||||
"VLMOpenVocabularyDetection": VLMOpenVocabularyDetection,
|
||||
}
|
||||
NODE_DISPLAY_NAME_MAPPINGS = {
|
||||
"VLMOpenVocabularyDetection": "VLM Open-Vocabulary Detection",
|
||||
}
|
||||
+1826
File diff suppressed because it is too large
Load Diff
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user