1.8.0
This commit is contained in:
 noembryo
@@ -1,18 +1,22 @@
|
||||
# noEmbryo Nodes
|
||||
A diverse set of nodes for ComfyUI.
|
||||
- [Json Prompt Loader](#json-prompt-loader)
|
||||
- [Load Image (from path)](#load-image-from-path)
|
||||
- [Resolution Scale](#resolution-scale)
|
||||
- [Regex Text Chopper](#regex-text-chopper)
|
||||
- [H3 Motion Context Clip Stitcher](#h3-motion-context-clip-stitcher)
|
||||
- [H3 Motion Context Clip Purge](#h3-motion-context-clip-purge)
|
||||
- [Auto Save Workflow](#auto-save-workflow)
|
||||
- [PromptTermList (1-6)](#prompttermlist-1-6)
|
||||
|
||||
[![made-with-python][Python]](https://www.python.org/) [![License: MIT][MIT]](LICENSE)
|
||||
A diverse set of nodes for ComfyUI.
|
||||
You can access them through "Add node > noEmbryo" submenu.
|
||||
|
||||
[![made-with-python][Python]](https://www.python.org/)
|
||||
[![License: MIT][MIT]](LICENSE)
|
||||
* [Json Prompt Loader](#json-prompt-loader)
|
||||
* [Load Image (from path)](#load-image-from-path)
|
||||
* [Image Composer](#image-composer)
|
||||
* [Resolution Scale](#resolution-scale)
|
||||
* [Regex Text Chopper](#regex-text-chopper)
|
||||
* [H3 Motion Context Clip Stitcher](#h3-motion-context-clip-stitcher)
|
||||
* [H3 Clip Refiner](#h3-clip-refiner)
|
||||
* [H3 Motion Context Clip Purge](#h3-motion-context-clip-purge)
|
||||
* [H3 AV Latent from Video](#h3-av-latent-from-video)
|
||||
* [H3 Context Latent Converter](#h3-context-latent-converter)
|
||||
* [Auto Save Workflow](#auto-save-workflow)
|
||||
* [PromptTermList 1-6](#prompttermlist-1-6)
|
||||
* [Installation](#installation)
|
||||
|
||||
---
|
||||
## Json Prompt Loader
|
||||
@@ -256,34 +260,6 @@ Encodes a whole video (IMAGE frames + AUDIO) with the MiniMax H3 VAEs into an AV
|
||||
A utility node that converts an `H3 Motion Context` archive latent (as loaded by `MiniMaxH3MotionContextLoadLatent`, whose 'samples' is a plain list) into the AV latent form that comfy-core's `LTXVSeparateAVLatent` expects (av_latent["samples"].unbind() -> (video, audio)).
|
||||
|
||||
|
||||
|
||||
---
|
||||
|
||||
## Replace Audio no Re-Encode
|
||||
|
||||

|
||||
A minimal ComfyUI custom node that replaces the audio stream of an existing video file with a new audio track, using ffmpeg's stream-copy mode for the video (`-c:v copy`). The video bitstream is remuxed losslessly and is never decoded/re-encoded, only the container is rewritten with a new audio stream. Requires ffmpeg to be installed and available on PATH.
|
||||
|
||||
- **Input**
|
||||
- **audio**: ComfyUI AUDIO signal (e.g. from Load Audio or a generated audio node) to use as the new audio stream.
|
||||
Ignored if audio_path is set.
|
||||
|
||||
- **Output**
|
||||
- **video_path** returns the path where the video is saved in text.
|
||||
|
||||
- **Controls**
|
||||
- **video_path** Path to the video file whose audio stream will be replaced (e.g. any .mp4/.mov/.mkv on disk).
|
||||
- **filename_prefix** Prefix for the output file name.
|
||||
The result is saved in the ComfyUI output directory as: <prefix>_<video name>_<counter>.<ext>
|
||||
- **audio_codec** How to encode the new audio stream:
|
||||
- aac: re-encode to AAC 192kbps (always used when the audio comes from the audio input)
|
||||
- copy: remux the audio file losslessly, without re-encoding (only meaningful when using the audio_path input)"
|
||||
- **audio_path** Path to an audio file, or a video file, whose audio stream will be extracted, to be used as the new audio stream.
|
||||
If set, it takes priority over the audio input.
|
||||
|
||||
|
||||
|
||||
|
||||
---
|
||||
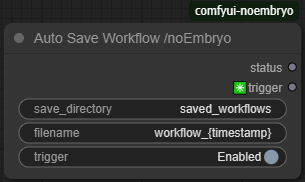
## Auto Save Workflow
|
||||
|
||||
|
||||
@@ -11,14 +11,14 @@ from .minimax import (H3MotionContextClipStitcher, H3ClipRefiner,
|
||||
H3MotionContextClipPurge, H3AVLatentFromVideo)
|
||||
|
||||
MANIFEST = {"name": "noEmbryo Nodes",
|
||||
"version": (1, 8, 0),
|
||||
"version": (1, 8, 1),
|
||||
"author": "noEmbryo",
|
||||
"project": "https://github.com/noembryo/ComfyUI-noEmbryo",
|
||||
"description": "Nodes for ComfyUI",
|
||||
"license": "MIT",
|
||||
}
|
||||
__author__ = "noEmbryo"
|
||||
__version__ = "1.8.0"
|
||||
__version__ = "1.8.1"
|
||||
|
||||
LISTS_PATH = join(dirname(realpath(__file__)), "TermLists")
|
||||
|
||||
@@ -482,202 +482,202 @@ class AutoSaveWorkflow:
|
||||
return (status,)
|
||||
|
||||
|
||||
class ReplaceAudioNoReEncode:
|
||||
""" A minimal ComfyUI custom node that replaces the audio stream of an existing
|
||||
video file with a new audio track, using ffmpeg's stream-copy mode for the
|
||||
video (`-c:v copy`). The video bitstream is remuxed losslessly and is never
|
||||
decoded/re-encoded — only the container is rewritten with a new audio stream.
|
||||
|
||||
Requires ffmpeg to be installed and available on PATH.
|
||||
|
||||
video_path : path to an existing encoded video file (e.g. output of
|
||||
VHS Video Combine, or any .mp4/.mov/.mkv on disk).
|
||||
audio : standard ComfyUI AUDIO type ({"waveform": tensor, "sample_rate": int}),
|
||||
e.g. from Load Audio, VHS audio output, or a generated audio node.
|
||||
"""
|
||||
|
||||
@classmethod
|
||||
def INPUT_TYPES(cls):
|
||||
return {
|
||||
"required": {
|
||||
"video_path": ("STRING", {"default": "", "multiline": False,
|
||||
"tooltip": "Path to the video file whose audio stream "
|
||||
"will be replaced (e.g. any .mp4/.mov/.mkv on disk)."}),
|
||||
"filename_prefix": ("STRING", {"default": "audio_replaced",
|
||||
"tooltip": "Prefix for the output file name.\n"
|
||||
"The result is saved in the ComfyUI output "
|
||||
"directory as:\n"
|
||||
"<prefix>_<video name>_<counter>.<ext>"}),
|
||||
"audio_codec": (["aac", "copy"], {"default": "aac",
|
||||
"tooltip": "How to encode the new audio stream:\n"
|
||||
"• aac: re-encode to AAC 192kbps (always "
|
||||
"used when the audio comes from the AUDIO "
|
||||
"tensor input)\n"
|
||||
"• copy: remux the audio file losslessly, "
|
||||
"without re-encoding (only meaningful when "
|
||||
"using the audio_path input)"}),
|
||||
},
|
||||
"optional": {
|
||||
"audio": ("AUDIO", {"tooltip": "ComfyUI AUDIO signal (e.g. from Load Audio or a "
|
||||
"generated audio node) to use as the new audio "
|
||||
"stream.\nIgnored if audio_path is set."}),
|
||||
"audio_path": ("STRING", {"default": "", "multiline": False,
|
||||
"tooltip": "Path to an audio file — or a video file, whose "
|
||||
"audio stream will be extracted — to use as the new "
|
||||
"audio stream. If set, it takes priority over the "
|
||||
"audio tensor input."}),
|
||||
"shortest": ("BOOLEAN", {"default": True,
|
||||
"tooltip": "If enabled and the audio is shorter/longer than "
|
||||
"the video, the output is trimmed to the "
|
||||
"shorter of the two streams."}),
|
||||
},
|
||||
"hidden": {
|
||||
"prompt": "PROMPT",
|
||||
"extra_pnginfo": "EXTRA_PNGINFO",
|
||||
},
|
||||
}
|
||||
|
||||
DESCRIPTION = ("Replaces the audio stream of a video file without re-encoding the video. "
|
||||
"The new audio comes either from an AUDIO tensor input or from an audio file "
|
||||
"given by audio_path. Requires ffmpeg on the PATH.")
|
||||
|
||||
RETURN_TYPES = ("STRING",)
|
||||
RETURN_NAMES = ("video_path",)
|
||||
OUTPUT_TOOLTIPS = ("The path of the output video file with the replaced audio stream.",)
|
||||
FUNCTION = "replace_audio"
|
||||
CATEGORY = "noEmbryo"
|
||||
OUTPUT_NODE = True
|
||||
|
||||
@staticmethod
|
||||
def _ffm_escape(text):
|
||||
""" Escapes a string for use as a value in an ffmetadata file """
|
||||
for ch in ("\\", "=", ";", "#", "\n"):
|
||||
text = text.replace(ch, "\\" + ch) if ch != "\n" else text.replace(ch, r"\n")
|
||||
return text
|
||||
|
||||
@staticmethod
|
||||
def write_wave_file(wave_path, waveform, sample_rate):
|
||||
""" Writes a waveform tensor to a wav file, using only the standard library
|
||||
"""
|
||||
import wave
|
||||
import numpy as np
|
||||
if waveform.dim() == 1: # [samples] -> [1, samples]
|
||||
waveform = waveform.unsqueeze(0)
|
||||
# [channels, samples] -> [samples, channels]
|
||||
samples = waveform.cpu().numpy().T
|
||||
samples = np.clip(samples, -1.0, 1.0)
|
||||
pcm = (samples * 32767.0).astype(np.int16)
|
||||
with wave.open(wave_path, "wb") as wf:
|
||||
wf.setnchannels(pcm.shape[1])
|
||||
wf.setsampwidth(2) # 2 bytes = 16 bit
|
||||
wf.setframerate(sample_rate)
|
||||
wf.writeframes(pcm.tobytes())
|
||||
|
||||
def replace_audio(self, video_path, filename_prefix, audio_codec,
|
||||
audio=None, audio_path="", shortest=True,
|
||||
prompt=None, extra_pnginfo=None):
|
||||
if not video_path or not os.path.isfile(video_path):
|
||||
raise FileNotFoundError(f"Video file not found: {video_path!r}")
|
||||
|
||||
output_dir = folder_paths.get_output_directory()
|
||||
os.makedirs(output_dir, exist_ok=True)
|
||||
|
||||
tmp_audio_path = None
|
||||
if audio_path:
|
||||
if not os.path.isfile(audio_path):
|
||||
raise FileNotFoundError(f"Audio file not found: {audio_path!r}")
|
||||
second_input = audio_path
|
||||
elif audio is not None:
|
||||
# --- Write the incoming AUDIO tensor to a temp wav file ---
|
||||
waveform = audio["waveform"]
|
||||
sample_rate = audio["sample_rate"]
|
||||
if waveform.dim() == 3: # [batch, channels, samples] -> take first item
|
||||
waveform = waveform[0]
|
||||
tmp_audio_fd, tmp_audio_path = tempfile.mkstemp(suffix=".wav")
|
||||
os.close(tmp_audio_fd)
|
||||
self.write_wave_file(tmp_audio_path, waveform, sample_rate)
|
||||
second_input = tmp_audio_path
|
||||
# Copying raw PCM into a container makes no sense, so force aac
|
||||
audio_codec = "aac"
|
||||
else:
|
||||
raise ValueError("No audio given: connect an AUDIO input or set audio_path.")
|
||||
|
||||
# --- Build a unique output path ---
|
||||
base_name = os.path.splitext(os.path.basename(video_path))[0]
|
||||
ext = os.path.splitext(video_path)[1] or ".mp4"
|
||||
# Start from max existing number + 1, so deleted files don't cause name reuse.
|
||||
# The prefix may contain subdirectories (e.g. "MMH3\NewAudio"), so the scan
|
||||
# must look in the directory the files are actually written to.
|
||||
out_path = os.path.join(output_dir, f"{filename_prefix}_{base_name}_001{ext}")
|
||||
scan_dir = os.path.dirname(out_path)
|
||||
os.makedirs(scan_dir, exist_ok=True)
|
||||
# listdir() returns bare filenames, so only the last component of the
|
||||
# prefix (without the directory part) can appear in them
|
||||
prefix_name = os.path.basename(filename_prefix.replace("\\", "/"))
|
||||
counter = 1
|
||||
pattern = re.compile(rf"^{re.escape(prefix_name)}_{re.escape(base_name)}"
|
||||
rf"_(\d+){re.escape(ext)}$")
|
||||
for fname in os.listdir(scan_dir):
|
||||
m = pattern.match(fname)
|
||||
if m:
|
||||
counter = max(counter, int(m.group(1)) + 1)
|
||||
out_name = f"{filename_prefix}_{base_name}_{counter:03d}{ext}"
|
||||
out_path = os.path.join(output_dir, out_name)
|
||||
|
||||
# --- Write the workflow metadata to a temp ffmetadata file ---
|
||||
# (avoids Windows command-line length limits that -metadata args would hit)
|
||||
meta_fd, meta_path = tempfile.mkstemp(suffix=".txt")
|
||||
os.close(meta_fd)
|
||||
with io.open(meta_path, "w", encoding="utf-8") as mf:
|
||||
mf.write(";FFMETADATA1\n")
|
||||
if prompt is not None:
|
||||
mf.write(f"prompt={self._ffm_escape(json.dumps(prompt))}\n")
|
||||
if extra_pnginfo and "workflow" in extra_pnginfo:
|
||||
mf.write(f"workflow={self._ffm_escape(json.dumps(extra_pnginfo['workflow']))}\n")
|
||||
|
||||
# --- ffmpeg: stream-copy the video, only touch the audio ---
|
||||
cmd = [
|
||||
"ffmpeg", "-y",
|
||||
"-i", video_path,
|
||||
"-i", second_input,
|
||||
"-i", meta_path,
|
||||
"-map", "0:v:0",
|
||||
"-map", "1:a:0",
|
||||
"-map_metadata", "2",
|
||||
"-c:v", "copy",
|
||||
]
|
||||
if audio_codec == "copy":
|
||||
cmd += ["-c:a", "copy"]
|
||||
else:
|
||||
cmd += ["-c:a", "aac", "-b:a", "192k"]
|
||||
# allow arbitrary metadata keys in these containers
|
||||
if ext.lower() in (".mp4", ".mov"):
|
||||
cmd += ["-movflags", "use_metadata_tags"]
|
||||
if shortest:
|
||||
cmd.append("-shortest")
|
||||
cmd.append(out_path)
|
||||
|
||||
def run_ffmpeg(command):
|
||||
return subprocess.run(command, capture_output=True, text=True)
|
||||
|
||||
try:
|
||||
result = run_ffmpeg(cmd)
|
||||
if result.returncode != 0 and audio_codec == "copy":
|
||||
# "copy" can fail when the source audio codec is incompatible with
|
||||
# the output container (e.g. PCM in an AVI -> mp4). Retry with aac.
|
||||
fallback_cmd = list(cmd)
|
||||
for i, arg in enumerate(fallback_cmd):
|
||||
if arg == "-c:a" and fallback_cmd[i + 1] == "copy":
|
||||
fallback_cmd[i + 1] = "aac"
|
||||
result = run_ffmpeg(fallback_cmd)
|
||||
if result.returncode != 0:
|
||||
raise RuntimeError(f"ffmpeg failed (exit {result.returncode}):\n{result.stderr}")
|
||||
finally:
|
||||
for tmp in (tmp_audio_path, meta_path):
|
||||
if tmp and os.path.exists(tmp):
|
||||
os.remove(tmp)
|
||||
|
||||
return (out_path,)
|
||||
# class ReplaceAudioNoReEncode:
|
||||
# """ A minimal ComfyUI custom node that replaces the audio stream of an existing
|
||||
# video file with a new audio track, using ffmpeg's stream-copy mode for the
|
||||
# video (`-c:v copy`). The video bitstream is remuxed losslessly and is never
|
||||
# decoded/re-encoded — only the container is rewritten with a new audio stream.
|
||||
#
|
||||
# Requires ffmpeg to be installed and available on PATH.
|
||||
#
|
||||
# video_path : path to an existing encoded video file (e.g. output of
|
||||
# VHS Video Combine, or any .mp4/.mov/.mkv on disk).
|
||||
# audio : standard ComfyUI AUDIO type ({"waveform": tensor, "sample_rate": int}),
|
||||
# e.g. from Load Audio, VHS audio output, or a generated audio node.
|
||||
# """
|
||||
#
|
||||
# @classmethod
|
||||
# def INPUT_TYPES(cls):
|
||||
# return {
|
||||
# "required": {
|
||||
# "video_path": ("STRING", {"default": "", "multiline": False,
|
||||
# "tooltip": "Path to the video file whose audio stream "
|
||||
# "will be replaced (e.g. any .mp4/.mov/.mkv on disk)."}),
|
||||
# "filename_prefix": ("STRING", {"default": "audio_replaced",
|
||||
# "tooltip": "Prefix for the output file name.\n"
|
||||
# "The result is saved in the ComfyUI output "
|
||||
# "directory as:\n"
|
||||
# "<prefix>_<video name>_<counter>.<ext>"}),
|
||||
# "audio_codec": (["aac", "copy"], {"default": "aac",
|
||||
# "tooltip": "How to encode the new audio stream:\n"
|
||||
# "• aac: re-encode to AAC 192kbps (always "
|
||||
# "used when the audio comes from the AUDIO "
|
||||
# "tensor input)\n"
|
||||
# "• copy: remux the audio file losslessly, "
|
||||
# "without re-encoding (only meaningful when "
|
||||
# "using the audio_path input)"}),
|
||||
# },
|
||||
# "optional": {
|
||||
# "audio": ("AUDIO", {"tooltip": "ComfyUI AUDIO signal (e.g. from Load Audio or a "
|
||||
# "generated audio node) to use as the new audio "
|
||||
# "stream.\nIgnored if audio_path is set."}),
|
||||
# "audio_path": ("STRING", {"default": "", "multiline": False,
|
||||
# "tooltip": "Path to an audio file — or a video file, whose "
|
||||
# "audio stream will be extracted — to use as the new "
|
||||
# "audio stream. If set, it takes priority over the "
|
||||
# "audio tensor input."}),
|
||||
# "shortest": ("BOOLEAN", {"default": True,
|
||||
# "tooltip": "If enabled and the audio is shorter/longer than "
|
||||
# "the video, the output is trimmed to the "
|
||||
# "shorter of the two streams."}),
|
||||
# },
|
||||
# "hidden": {
|
||||
# "prompt": "PROMPT",
|
||||
# "extra_pnginfo": "EXTRA_PNGINFO",
|
||||
# },
|
||||
# }
|
||||
#
|
||||
# DESCRIPTION = ("Replaces the audio stream of a video file without re-encoding the video. "
|
||||
# "The new audio comes either from an AUDIO tensor input or from an audio file "
|
||||
# "given by audio_path. Requires ffmpeg on the PATH.")
|
||||
#
|
||||
# RETURN_TYPES = ("STRING",)
|
||||
# RETURN_NAMES = ("video_path",)
|
||||
# OUTPUT_TOOLTIPS = ("The path of the output video file with the replaced audio stream.",)
|
||||
# FUNCTION = "replace_audio"
|
||||
# CATEGORY = "noEmbryo"
|
||||
# OUTPUT_NODE = True
|
||||
#
|
||||
# @staticmethod
|
||||
# def _ffm_escape(text):
|
||||
# """ Escapes a string for use as a value in an ffmetadata file """
|
||||
# for ch in ("\\", "=", ";", "#", "\n"):
|
||||
# text = text.replace(ch, "\\" + ch) if ch != "\n" else text.replace(ch, r"\n")
|
||||
# return text
|
||||
#
|
||||
# @staticmethod
|
||||
# def write_wave_file(wave_path, waveform, sample_rate):
|
||||
# """ Writes a waveform tensor to a wav file, using only the standard library
|
||||
# """
|
||||
# import wave
|
||||
# import numpy as np
|
||||
# if waveform.dim() == 1: # [samples] -> [1, samples]
|
||||
# waveform = waveform.unsqueeze(0)
|
||||
# # [channels, samples] -> [samples, channels]
|
||||
# samples = waveform.cpu().numpy().T
|
||||
# samples = np.clip(samples, -1.0, 1.0)
|
||||
# pcm = (samples * 32767.0).astype(np.int16)
|
||||
# with wave.open(wave_path, "wb") as wf:
|
||||
# wf.setnchannels(pcm.shape[1])
|
||||
# wf.setsampwidth(2) # 2 bytes = 16 bit
|
||||
# wf.setframerate(sample_rate)
|
||||
# wf.writeframes(pcm.tobytes())
|
||||
#
|
||||
# def replace_audio(self, video_path, filename_prefix, audio_codec,
|
||||
# audio=None, audio_path="", shortest=True,
|
||||
# prompt=None, extra_pnginfo=None):
|
||||
# if not video_path or not os.path.isfile(video_path):
|
||||
# raise FileNotFoundError(f"Video file not found: {video_path!r}")
|
||||
#
|
||||
# output_dir = folder_paths.get_output_directory()
|
||||
# os.makedirs(output_dir, exist_ok=True)
|
||||
#
|
||||
# tmp_audio_path = None
|
||||
# if audio_path:
|
||||
# if not os.path.isfile(audio_path):
|
||||
# raise FileNotFoundError(f"Audio file not found: {audio_path!r}")
|
||||
# second_input = audio_path
|
||||
# elif audio is not None:
|
||||
# # --- Write the incoming AUDIO tensor to a temp wav file ---
|
||||
# waveform = audio["waveform"]
|
||||
# sample_rate = audio["sample_rate"]
|
||||
# if waveform.dim() == 3: # [batch, channels, samples] -> take first item
|
||||
# waveform = waveform[0]
|
||||
# tmp_audio_fd, tmp_audio_path = tempfile.mkstemp(suffix=".wav")
|
||||
# os.close(tmp_audio_fd)
|
||||
# self.write_wave_file(tmp_audio_path, waveform, sample_rate)
|
||||
# second_input = tmp_audio_path
|
||||
# # Copying raw PCM into a container makes no sense, so force aac
|
||||
# audio_codec = "aac"
|
||||
# else:
|
||||
# raise ValueError("No audio given: connect an AUDIO input or set audio_path.")
|
||||
#
|
||||
# # --- Build a unique output path ---
|
||||
# base_name = os.path.splitext(os.path.basename(video_path))[0]
|
||||
# ext = os.path.splitext(video_path)[1] or ".mp4"
|
||||
# # Start from max existing number + 1, so deleted files don't cause name reuse.
|
||||
# # The prefix may contain subdirectories (e.g. "MMH3\NewAudio"), so the scan
|
||||
# # must look in the directory the files are actually written to.
|
||||
# out_path = os.path.join(output_dir, f"{filename_prefix}_{base_name}_001{ext}")
|
||||
# scan_dir = os.path.dirname(out_path)
|
||||
# os.makedirs(scan_dir, exist_ok=True)
|
||||
# # listdir() returns bare filenames, so only the last component of the
|
||||
# # prefix (without the directory part) can appear in them
|
||||
# prefix_name = os.path.basename(filename_prefix.replace("\\", "/"))
|
||||
# counter = 1
|
||||
# pattern = re.compile(rf"^{re.escape(prefix_name)}_{re.escape(base_name)}"
|
||||
# rf"_(\d+){re.escape(ext)}$")
|
||||
# for fname in os.listdir(scan_dir):
|
||||
# m = pattern.match(fname)
|
||||
# if m:
|
||||
# counter = max(counter, int(m.group(1)) + 1)
|
||||
# out_name = f"{filename_prefix}_{base_name}_{counter:03d}{ext}"
|
||||
# out_path = os.path.join(output_dir, out_name)
|
||||
#
|
||||
# # --- Write the workflow metadata to a temp ffmetadata file ---
|
||||
# # (avoids Windows command-line length limits that -metadata args would hit)
|
||||
# meta_fd, meta_path = tempfile.mkstemp(suffix=".txt")
|
||||
# os.close(meta_fd)
|
||||
# with io.open(meta_path, "w", encoding="utf-8") as mf:
|
||||
# mf.write(";FFMETADATA1\n")
|
||||
# if prompt is not None:
|
||||
# mf.write(f"prompt={self._ffm_escape(json.dumps(prompt))}\n")
|
||||
# if extra_pnginfo and "workflow" in extra_pnginfo:
|
||||
# mf.write(f"workflow={self._ffm_escape(json.dumps(extra_pnginfo['workflow']))}\n")
|
||||
#
|
||||
# # --- ffmpeg: stream-copy the video, only touch the audio ---
|
||||
# cmd = [
|
||||
# "ffmpeg", "-y",
|
||||
# "-i", video_path,
|
||||
# "-i", second_input,
|
||||
# "-i", meta_path,
|
||||
# "-map", "0:v:0",
|
||||
# "-map", "1:a:0",
|
||||
# "-map_metadata", "2",
|
||||
# "-c:v", "copy",
|
||||
# ]
|
||||
# if audio_codec == "copy":
|
||||
# cmd += ["-c:a", "copy"]
|
||||
# else:
|
||||
# cmd += ["-c:a", "aac", "-b:a", "192k"]
|
||||
# # allow arbitrary metadata keys in these containers
|
||||
# if ext.lower() in (".mp4", ".mov"):
|
||||
# cmd += ["-movflags", "use_metadata_tags"]
|
||||
# if shortest:
|
||||
# cmd.append("-shortest")
|
||||
# cmd.append(out_path)
|
||||
#
|
||||
# def run_ffmpeg(command):
|
||||
# return subprocess.run(command, capture_output=True, text=True)
|
||||
#
|
||||
# try:
|
||||
# result = run_ffmpeg(cmd)
|
||||
# if result.returncode != 0 and audio_codec == "copy":
|
||||
# # "copy" can fail when the source audio codec is incompatible with
|
||||
# # the output container (e.g. PCM in an AVI -> mp4). Retry with aac.
|
||||
# fallback_cmd = list(cmd)
|
||||
# for i, arg in enumerate(fallback_cmd):
|
||||
# if arg == "-c:a" and fallback_cmd[i + 1] == "copy":
|
||||
# fallback_cmd[i + 1] = "aac"
|
||||
# result = run_ffmpeg(fallback_cmd)
|
||||
# if result.returncode != 0:
|
||||
# raise RuntimeError(f"ffmpeg failed (exit {result.returncode}):\n{result.stderr}")
|
||||
# finally:
|
||||
# for tmp in (tmp_audio_path, meta_path):
|
||||
# if tmp and os.path.exists(tmp):
|
||||
# os.remove(tmp)
|
||||
#
|
||||
# return (out_path,)
|
||||
|
||||
|
||||
NODE_CLASS_MAPPINGS = {f"JsonPromptLoader -{__author__}": JsonPromptLoader,
|
||||
@@ -691,7 +691,7 @@ NODE_CLASS_MAPPINGS = {f"JsonPromptLoader -{__author__}": JsonPromptLoader,
|
||||
f"H3MotionContextClipPurge -{__author__}": H3MotionContextClipPurge,
|
||||
f"H3ContextLatentConverter -{__author__}": H3ContextLatentConverter,
|
||||
f"H3AVLatentFromVideo -{__author__}": H3AVLatentFromVideo,
|
||||
f"ReplaceAudioNoReEncode -{__author__}": ReplaceAudioNoReEncode,
|
||||
# f"ReplaceAudioNoReEncode -{__author__}": ReplaceAudioNoReEncode,
|
||||
"PromptTermList1": PromptTermList1,
|
||||
"PromptTermList2": PromptTermList2,
|
||||
"PromptTermList3": PromptTermList3,
|
||||
@@ -711,7 +711,7 @@ NODE_DISPLAY_NAME_MAPPINGS = {f"JsonPromptLoader -{__author__}": f"Json Prompt L
|
||||
f"H3MotionContextClipPurge -{__author__}": f"H3 Motion Context Clip Purge /{__author__}",
|
||||
f"H3ContextLatentConverter -{__author__}": f"H3 Context Latent Converter /{__author__}",
|
||||
f"H3AVLatentFromVideo -{__author__}": f"H3 AV Latent from Video /{__author__}",
|
||||
f"ReplaceAudioNoReEncode -{__author__}": f"Replace Audio no ReEncode /{__author__}",
|
||||
# f"ReplaceAudioNoReEncode -{__author__}": f"Replace Audio no ReEncode /{__author__}",
|
||||
"PromptTermList1": f"PromptTermList 1 /{__author__}",
|
||||
"PromptTermList2": f"PromptTermList 2 /{__author__}",
|
||||
"PromptTermList3": f"PromptTermList 3 /{__author__}",
|
||||
|
||||
+1
-1
@@ -12,7 +12,7 @@ limit the output's size in megapixels. \n
|
||||
* "PromptTermList (1-6)" nodes to help with the creation of Prompts. \n
|
||||
* "Auto Save Workflow" can save the current workflow to a .json file automatically. \n
|
||||
"""
|
||||
version = "1.8.0"
|
||||
version = "1.8.1"
|
||||
license = {text = "MIT License"}
|
||||
dependencies = []
|
||||
|
||||
|
||||
Reference in New Issue
Block a user