Update README.md
This commit is contained in:
 shootthesound
@@ -6,7 +6,11 @@
|
||||
- **Chunked generation (best use case)**: Stable motion provides clean anchors AND makes the next chunk far more likely to correctly continue the direction of a given action
|
||||
- **Single generation**: Smooths motion reversal and "ping-pong" in 81+ frame generations
|
||||
|
||||
See Demo Workflows in Folder and [demo clip here](https://youtu.be/wZgoklsVplc)
|
||||
Works with both **i2v** (image-to-video) and **t2v** (text-to-video), though i2v sees the most benefit due to anchor-based continuation.
|
||||
|
||||
See Demo Workflows in Folder and demo clip below:
|
||||
|
||||
[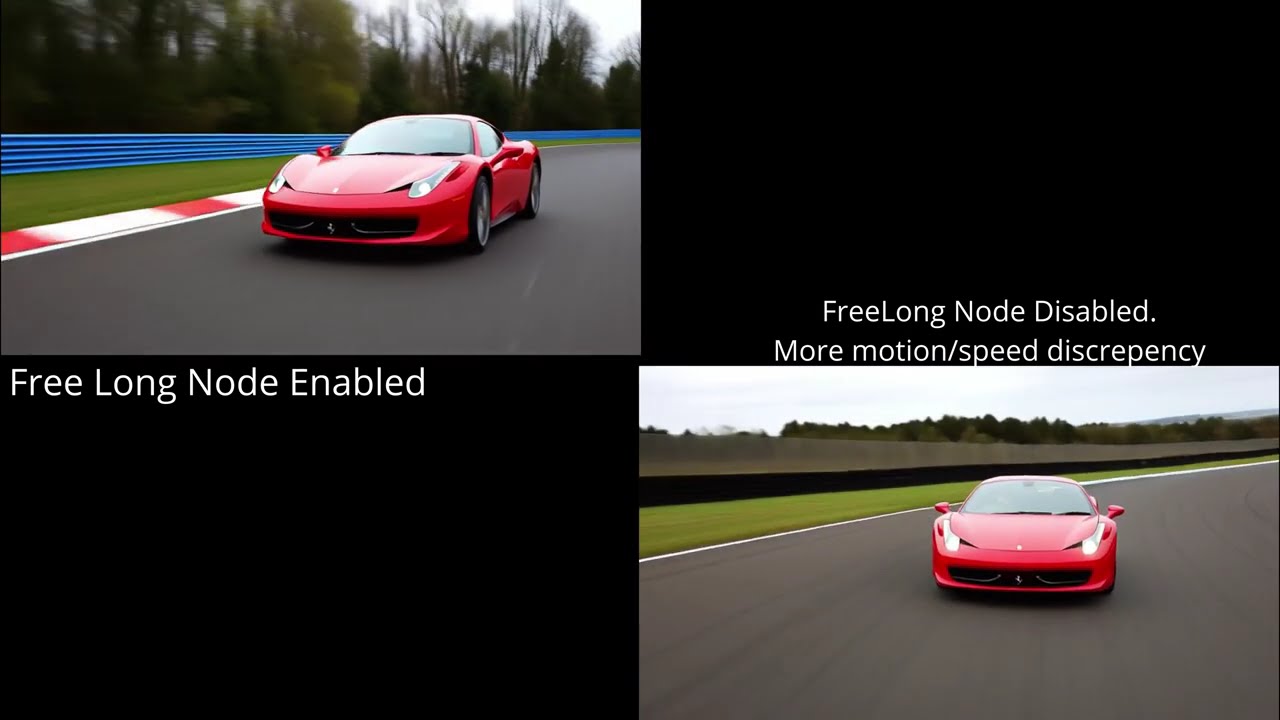](https://youtu.be/wZgoklsVplc)
|
||||
|
||||
If you find this useful:
|
||||
|
||||
@@ -22,10 +26,10 @@ Based on [FreeLong (NeurIPS 2024)](https://arxiv.org/abs/2407.19918), this imple
|
||||
|
||||
| Without FreeLong | With FreeLong |
|
||||
|------------------|---------------|
|
||||
| Motion reverses mid-video ("ping-pong") | Stable directional motion throughout |
|
||||
| Subject drifts between "scenes" | Consistent subject appearance |
|
||||
| Prompt partially ignored for motion | Motion follows prompt intent |
|
||||
| 2-3 distinct "scenes" per generation | Single coherent sequence |
|
||||
| More prone to motion reversal ("ping-pong") | More likely to maintain stable direction |
|
||||
| More prone to subject drift between "scenes" | More likely to keep consistent appearance |
|
||||
| More prone to ignoring motion in prompt | More likely to follow prompt intent |
|
||||
| More prone to multiple distinct "scenes" | More likely to produce coherent sequence |
|
||||
|
||||
**How it works:**
|
||||
- **Global stream**: Full-sequence attention captures overall motion direction
|
||||
|
||||
Reference in New Issue
Block a user