
comfyUI-LongLook
Consistent motion and prompt adherence for Wan 2.2 video generation.
TL;DR:
- Chunked generation (best use case): Stable motion provides clean anchors AND makes the next chunk far more likely to correctly continue the direction of a given action
- Single generation: Smooths motion reversal and "ping-pong" in 81+ frame generations
Works with both i2v (image-to-video) and t2v (text-to-video), though i2v sees the most benefit due to anchor-based continuation.
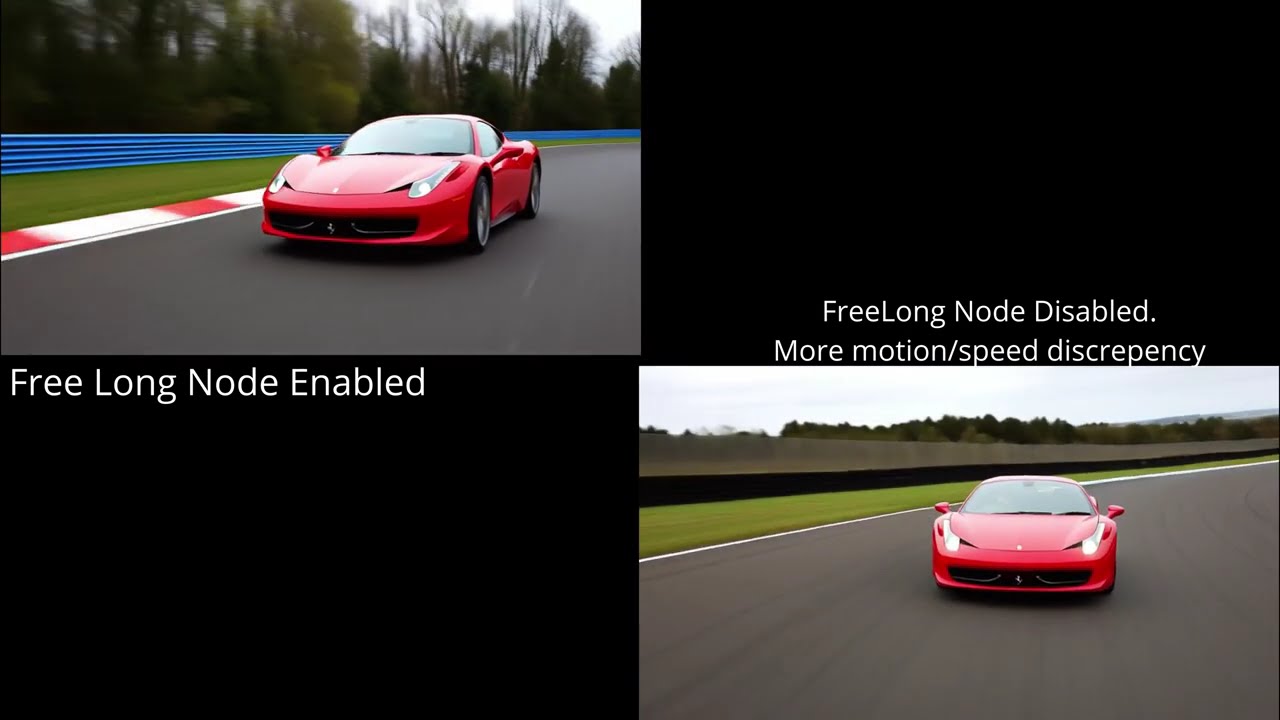
See Demo Workflows in Folder and demo clip below:
If you find this useful:

What It Does
The Core: FreeLong Spectral Blending
Based on FreeLong (NeurIPS 2024), this implements frequency-aware attention blending that dramatically improves motion consistency:
| Without FreeLong | With FreeLong |
|---|---|
| More prone to motion reversal ("ping-pong") | More likely to maintain stable direction |
| More prone to subject drift between "scenes" | More likely to keep consistent appearance |
| More prone to ignoring motion in prompt | More likely to follow prompt intent |
| More prone to multiple distinct "scenes" | More likely to produce coherent sequence |
How it works:
- Global stream: Full-sequence attention captures overall motion direction
- Local stream: Windowed attention preserves sharp details
- Spectral blend: FFT combines low frequencies (motion) from global + high frequencies (detail) from local
This is essentially motion-level prompt enforcement - the model maintains its initial motion intent rather than "forgetting" mid-generation.
The Bonus: Unlimited Length via Chunking
FreeLong's stable motion interpretation is what makes reliable chunk chaining possible:
[Chunk 1: 81 frames] → last frame → [Chunk 2: 81 frames] → last frame → [Chunk 3...] → ∞
Why this works:
Without FreeLong, chunk boundaries can often fail because:
- Motion may have reversed mid-chunk → last frame has wrong direction
- Subject drifted → last frame doesn't match earlier frames
- Ambiguous anchor → next chunk likely misinterprets intended motion
With FreeLong, each chunk has:
- Consistent motion direction throughout → last frame shows correct direction
- Stable subject interpretation → clean visual handoff
- Clear motion cues → next chunk far more likely to correctly continue
Two-sided benefit: FreeLong provides clean anchor frames AND makes the next generation far more likely to correctly interpret the motion direction. Clear input signals lead to better continuation.
Additional chunking benefits:
- Different prompts per chunk (scene evolution)
- Constant VRAM (no scaling with length)
- Fresh anchor resets any accumulated drift
Wan 2.2's attention mechanism struggles with temporal coherence:
- Native context is 81 frames (~5 seconds)
- Motion often reverses or drifts within that window
- Extending beyond 81 frames compounds these issues
Installation
- Clone into ComfyUI custom_nodes:
cd ComfyUI/custom_nodes
git clone https://github.com/shootthesound/comfyUI-LongLook.git
-
Restart ComfyUI
-
Load example workflow from
examples/Car-Racing-Example.jsonand Single-Shot-Example.json
Quick Start
Single Generation (Improved Motion)
Just add WanFreeLong before your sampler:
Load Model → WanFreeLong → KSampler → VAE Decode
Even without chunking, you get more consistent motion within 81 frames.
Chained Generation (Unlimited Length)
[Chunk 1]
Image → WanImageToVideo → FreeLong → Sampler → VAE Decode
                                                      ↓
                                                [Last Frame]
                                                      ↓
[Chunk 2]
FreeLong → WanContinuationConditioning → Sampler → VAE Decode
                    ↑                                    ↓
              [New Prompt]                         [Last Frame]
                                                        ↓
[Chunk 3...]                                        [Repeat]
Nodes
WanFreeLong (Spectral Blend)
Patches Wan model for FreeLong spectral blending.
| Parameter | Default | Description |
|---|---|---|
| enabled | true | Toggle for A/B testing |
| blend_strength | 0.7 | Spectral blend strength (0=off, 1=full) |
| low_freq_ratio | 0.5 | Portion of spectrum from global stream |
| local_window_frames | 33 | Video frames for detail window (~40% of total recommended) |
| blend_start_block | 0 | First transformer block to apply |
| blend_end_block | -1 | Last block (-1 = all) |
Optimal settings: blend_strength=0.8, low_freq_ratio=0.8, local_window_frames=33 for 81-frame videos
WanContinuationConditioning
Creates i2v conditioning from previous chunk's last frame.
| Parameter | Default | Description |
|---|---|---|
| width | 512 | Output video width |
| height | 512 | Output video height |
| video_frames | 81 | Frames to generate |
Inputs: positive, negative, anchor_images (from previous VAE decode), vae
Workflows
Basic Continuation (anchor_blend_workflow.json)
Two chunks, shared prompts. Extends a single scene.
Multi-Prompt (multi_prompt_workflow.json)
Different prompt per chunk for scene evolution:
- Chunk 1: "car driving on highway"
- Chunk 2: "car enters city streets"
- Chunk 3: "car parks at destination"
Same car, smooth motion, continuous narrative.
Parameter Tuning
| Goal | Adjustment |
|---|---|
| More motion consistency | Increase blend_strength (0.7-0.9) |
| More detail/sharpness | Decrease blend_strength (0.4-0.6) |
| Smoother motion | Increase low_freq_ratio (0.5-0.7) |
| More dynamic motion | Decrease low_freq_ratio (0.3-0.4) |
| Less morphing | Increase local_window_frames (49-65) |
Technical Details
FreeLong Implementation
- Dual-stream processing at transformer block level
- 50% overlapping windows with cosine crossfade
- Complementary FFT filters (low + high = 1.0)
- RoPE embeddings properly sliced per window
- Float32 FFT operations for numerical stability
Continuation Conditioning
- Last frame extracted from decoded video (float32, no 8-bit quantization)
- Re-encoded as i2v conditioning via VAE
- Proper mask format for Wan's conditioning system
Memory Efficiency
- Each chunk processes independently
- Only last frame passed between chunks
- No VRAM accumulation across chains
- Unlimited chunk count
- 8GB+ VRAM compatible
Experimental: Beyond 81 Frames
FreeLong was designed to extend beyond training length. You may be able to generate 97, 113, or more frames in a single pass. Trade-offs:
- VRAM scales with frame count
- Quality may degrade at extreme lengths
- Chunking approach is proven stable
Requirements
- ComfyUI
- Wan 2.2 models (i2v recommended)
- VideoHelperSuite (for video output)
Credits
- FreeLong paper: arxiv.org/abs/2407.19918
- Wan 2.2: Alibaba
- Implementation: Collaborative human-AI development
License
MIT