Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 KingManiya |
65983de336 | ||
|
KingManiya
|
e7ae6903c7 | ||
|
KingManiya
|
a04d1eae2b | ||
|
KingManiya
|
512c3f6906 | ||
|
KingManiya
|
bcfd05d1e5 | ||
|
KingManiya
|
96f9cffb5d | ||
|
KingManiya
|
73906c5d6a | ||
|
KingManiya
|
335a97f97f |
@@ -4,3 +4,4 @@ vendor
|
||||
__pycache__/
|
||||
*.py[cod]
|
||||
.pytest_cache/
|
||||
tests/.env
|
||||
|
||||
@@ -1,22 +1,28 @@
|
||||
# ComfyUI LLM Text Processor
|
||||
|
||||
Process text and images with GGUF LLMs in ComfyUI using llama.cpp, including
|
||||
Qwen3-VL, Qwen3.5, Qwen3.6, Gemma 4, and gpt-oss.
|
||||
Qwen3-VL, Qwen3.5, Qwen3.6, Qwen3.7, Qwen3.8, Gemma 4, and gpt-oss.
|
||||
|
||||
This extension adds a local LLM node for prompt writing, prompt rewriting,
|
||||
translation, captioning, extraction, and other text processing tasks inside
|
||||
ComfyUI. It discovers local GGUF models from `ComfyUI/models/LLM`, and it can
|
||||
also accept an image for multimodal models that use an external `mmproj`.
|
||||
also accept a single image or a ComfyUI image batch for multimodal models that
|
||||
use an external `mmproj`.
|
||||
|
||||
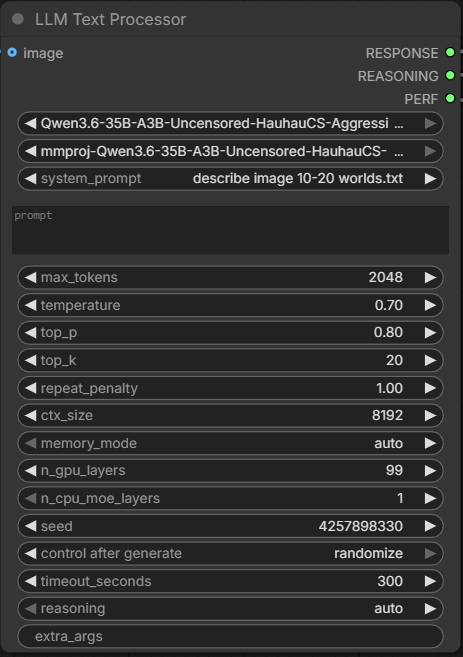
|
||||
|
||||
## Features
|
||||
|
||||
- Text generation and text transformation with local GGUF models
|
||||
- Optional image input for multimodal llama.cpp models that use `mmproj`
|
||||
- Optional image input for multimodal llama.cpp models that use `mmproj`,
|
||||
including multi-image batches
|
||||
- Separate `RESPONSE` and `REASONING` outputs
|
||||
- System prompt presets from text files
|
||||
- Recursive model discovery from `ComfyUI/models/LLM`
|
||||
- Automatic llama.cpp setup on supported Windows systems
|
||||
- Download progress logs during automatic llama.cpp setup
|
||||
- Advanced llama.cpp options for users who need them
|
||||
- Optional `enable_processing` toggle for switching between node processing and direct passthrough
|
||||
|
||||
## Supported Model Families
|
||||
|
||||
@@ -25,7 +31,7 @@ llama.cpp-compatible families.
|
||||
|
||||
Common examples:
|
||||
|
||||
- Qwen text and vision families such as `Qwen3-VL`, `Qwen3.5`, and `Qwen3.6`
|
||||
- Qwen text and vision families such as `Qwen3-VL`, `Qwen3.5`, `Qwen3.6`, `Qwen3.7`, and `Qwen3.8`
|
||||
- Gemma 4 GGUF models such as `gemma-4-E2B`, `gemma-4-E4B`,
|
||||
`gemma-4-26b-a4b`, and `gemma-4-31b`
|
||||
- OpenAI `gpt-oss-20b` and `gpt-oss-120b`
|
||||
@@ -63,6 +69,9 @@ LLM Text Processor -> LLM Text Processor
|
||||
|
||||
No extra setup is needed for basic use.
|
||||
|
||||
### Example workflow
|
||||
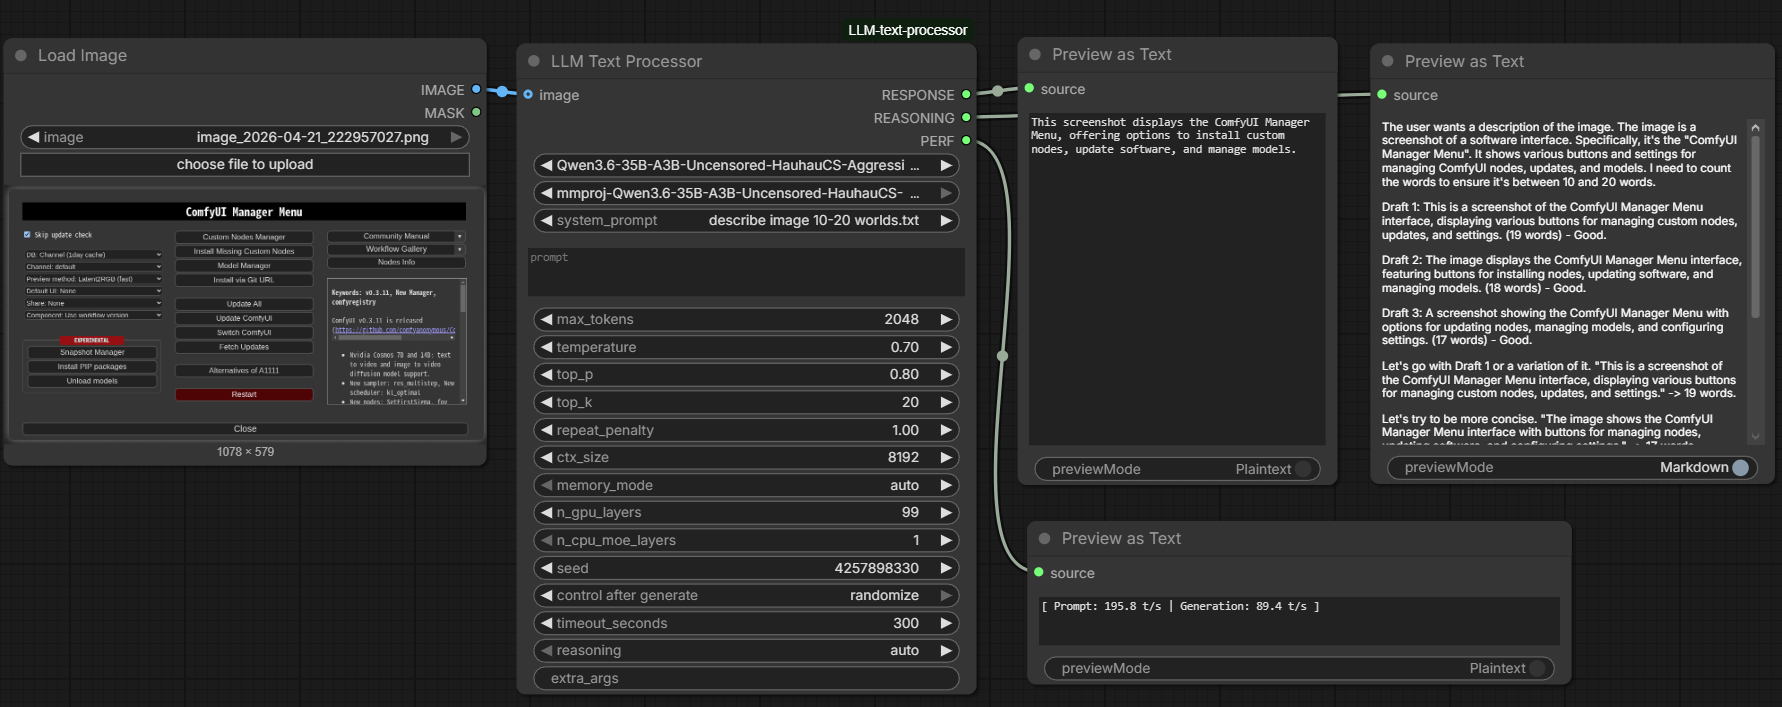
|
||||
|
||||
## llama.cpp
|
||||
|
||||
The node uses official llama.cpp release binaries. Automatic setup is currently
|
||||
@@ -76,6 +85,10 @@ Other platforms require manual setup.
|
||||
|
||||
The extension downloads llama.cpp only. It does not download model weights.
|
||||
|
||||
During automatic setup, the console shows download progress, total size when
|
||||
available, and current download speed so slow connections do not look like a
|
||||
freeze.
|
||||
|
||||
## Model Placement
|
||||
|
||||
Put your GGUF files anywhere under:
|
||||
@@ -95,7 +108,8 @@ The `model` dropdown shows model `.gguf` files. The `mmproj` dropdown shows
|
||||
vision projector files and `none`.
|
||||
|
||||
For image workflows, choose the `mmproj` file that belongs to the selected
|
||||
model. The node uses only the first image from a ComfyUI image batch.
|
||||
model. You can connect either one image or a ComfyUI image batch; batch items
|
||||
are sent together in the same llama.cpp request.
|
||||
|
||||
## System Prompt Presets
|
||||
|
||||
@@ -193,7 +207,7 @@ Reference: [gpt-oss docs](https://github.com/openai/gpt-oss)
|
||||
| Input | Description |
|
||||
| --- | --- |
|
||||
| `model` | GGUF model file from `ComfyUI/models/LLM`. |
|
||||
| `mmproj` | Vision projector GGUF. Required when using image input. |
|
||||
| `mmproj` | Vision projector GGUF. Required when using image input, whether it is one image or a batch. |
|
||||
| `system_prompt` | Prompt preset from `models/LLM/prompts`, or `none`. |
|
||||
| `prompt` | User prompt sent to the selected model. |
|
||||
| `max_tokens` | Maximum generated tokens. |
|
||||
@@ -208,16 +222,17 @@ Reference: [gpt-oss docs](https://github.com/openai/gpt-oss)
|
||||
| `seed` | Random seed. Use `-1` for a random seed. |
|
||||
| `timeout_seconds` | Maximum runtime before generation is stopped. |
|
||||
| `reasoning` | Reasoning output mode: `auto`, `on`, or `off`. |
|
||||
| `image` | Optional ComfyUI image input. Uses the first image in a batch. |
|
||||
| `image` | Optional image input. Accepts a single image or a ComfyUI batch, and sends the batch together to llama.cpp. |
|
||||
| `enable_processing` | When enabled, the node runs normally. When disabled, the node forwards `prompt` directly to `RESPONSE` and skips all model checks and llama.cpp execution. |
|
||||
| `extra_args` | Optional advanced llama.cpp parameters. Leave empty for normal use. |
|
||||
|
||||
## Node Outputs
|
||||
|
||||
| Output | Description |
|
||||
| --- | --- |
|
||||
| `RESPONSE` | Final model response with reasoning blocks removed. |
|
||||
| `REASONING` | Extracted reasoning when present in model output. |
|
||||
| `PERF` | Prompt and generation speed reported by llama.cpp. |
|
||||
| `RESPONSE` | Final model response with reasoning blocks removed, or the input `prompt` when `enable_processing` is disabled. |
|
||||
| `REASONING` | Extracted reasoning when present in model output. Empty when `enable_processing` is disabled. |
|
||||
| `PERF` | Prompt and generation speed reported by llama.cpp. Empty when `enable_processing` is disabled. |
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 336 KiB |

Binary file not shown.
|
After Width: | Height: | Size: 77 KiB |
+63
-9
@@ -3,7 +3,7 @@ from __future__ import annotations
|
||||
import fnmatch
|
||||
import json
|
||||
import platform
|
||||
import shutil
|
||||
import time
|
||||
import urllib.request
|
||||
import zipfile
|
||||
from dataclasses import dataclass
|
||||
@@ -11,7 +11,7 @@ from pathlib import Path
|
||||
from tempfile import TemporaryDirectory
|
||||
|
||||
|
||||
LLAMA_CPP_RELEASE_TAG = "b8840"
|
||||
LLAMA_CPP_RELEASE_TAG = "b10472"
|
||||
RELEASE_API_URL = f"https://api.github.com/repos/ggml-org/llama.cpp/releases/tags/{LLAMA_CPP_RELEASE_TAG}"
|
||||
PACKAGE_ROOT = Path(__file__).resolve().parent
|
||||
VENDOR_ROOT = PACKAGE_ROOT / "vendor" / "llama.cpp"
|
||||
@@ -62,11 +62,69 @@ def _json_get(url: str) -> dict:
|
||||
return json.loads(response.read().decode("utf-8"))
|
||||
|
||||
|
||||
def _format_size(num_bytes: float) -> str:
|
||||
units = ("B", "KB", "MB", "GB")
|
||||
value = float(num_bytes)
|
||||
for unit in units:
|
||||
if value < 1024 or unit == units[-1]:
|
||||
if unit == "B":
|
||||
return f"{int(value)} {unit}"
|
||||
return f"{value:.1f} {unit}"
|
||||
value /= 1024
|
||||
return f"{value:.1f} GB"
|
||||
|
||||
|
||||
def _download(url: str, destination: Path) -> None:
|
||||
request = urllib.request.Request(url, headers={"User-Agent": "ComfyUI-LLM-text-processor"})
|
||||
with urllib.request.urlopen(request, timeout=120) as response:
|
||||
total_size = response.headers.get("Content-Length")
|
||||
total_size = int(total_size) if total_size is not None else None
|
||||
downloaded = 0
|
||||
chunk_size = 1024 * 256
|
||||
started_at = time.monotonic()
|
||||
last_reported_at = started_at
|
||||
|
||||
with destination.open("wb") as handle:
|
||||
shutil.copyfileobj(response, handle)
|
||||
while True:
|
||||
chunk = response.read(chunk_size)
|
||||
if not chunk:
|
||||
break
|
||||
handle.write(chunk)
|
||||
downloaded += len(chunk)
|
||||
|
||||
now = time.monotonic()
|
||||
if now - last_reported_at < 1.0:
|
||||
continue
|
||||
|
||||
elapsed = max(now - started_at, 0.001)
|
||||
speed = downloaded / elapsed
|
||||
if total_size:
|
||||
percent = (downloaded / total_size) * 100
|
||||
print(
|
||||
"[LLM Text Processor] "
|
||||
f"Downloaded {_format_size(downloaded)} / {_format_size(total_size)} "
|
||||
f"({percent:.1f}%) at {_format_size(speed)}/s"
|
||||
)
|
||||
else:
|
||||
print(
|
||||
"[LLM Text Processor] "
|
||||
f"Downloaded {_format_size(downloaded)} at {_format_size(speed)}/s"
|
||||
)
|
||||
last_reported_at = now
|
||||
|
||||
elapsed = max(time.monotonic() - started_at, 0.001)
|
||||
speed = downloaded / elapsed
|
||||
if total_size:
|
||||
print(
|
||||
"[LLM Text Processor] "
|
||||
f"Finished download: {_format_size(downloaded)} / {_format_size(total_size)} "
|
||||
f"(100.0%) at {_format_size(speed)}/s"
|
||||
)
|
||||
else:
|
||||
print(
|
||||
"[LLM Text Processor] "
|
||||
f"Finished download: {_format_size(downloaded)} at {_format_size(speed)}/s"
|
||||
)
|
||||
|
||||
|
||||
def _select_assets(release: dict, spec: PlatformSpec) -> list[dict]:
|
||||
@@ -116,12 +174,8 @@ def _is_complete_install(install_dir: Path, spec: PlatformSpec) -> bool:
|
||||
|
||||
|
||||
def _existing_install(spec: PlatformSpec) -> LlamaCliPaths | None:
|
||||
if not VENDOR_ROOT.exists():
|
||||
return None
|
||||
for install_dir in VENDOR_ROOT.glob(f"*/{spec.key}"):
|
||||
if _is_complete_install(install_dir, spec):
|
||||
return _find_cli_paths(install_dir, spec)
|
||||
return None
|
||||
install_dir = VENDOR_ROOT / LLAMA_CPP_RELEASE_TAG / spec.key
|
||||
return _find_cli_paths(install_dir, spec) if _is_complete_install(install_dir, spec) else None
|
||||
|
||||
|
||||
def _extract_assets(assets: list[dict], install_dir: Path) -> None:
|
||||
|
||||
+13
-10
@@ -27,14 +27,10 @@ LLAMA_SEED_MODULUS = 2**32
|
||||
MAX_LLAMA_SEED = LLAMA_SEED_MODULUS - 1
|
||||
|
||||
|
||||
def tensor_to_temp_png(image) -> Path:
|
||||
def _tensor_to_temp_png(tensor) -> Path:
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
# ComfyUI IMAGE is normally B,H,W,C. The node uses the first batch item in v1.
|
||||
tensor = image
|
||||
if hasattr(tensor, "dim") and tensor.dim() == 4:
|
||||
tensor = tensor[0]
|
||||
array = (tensor.detach().cpu().numpy() * 255).clip(0, 255).astype(np.uint8)
|
||||
pil_image = Image.fromarray(array)
|
||||
fd, path = tempfile.mkstemp(prefix="llm-text-processor-", suffix=".png")
|
||||
@@ -43,6 +39,13 @@ def tensor_to_temp_png(image) -> Path:
|
||||
return Path(path)
|
||||
|
||||
|
||||
def tensor_to_temp_pngs(image) -> list[Path]:
|
||||
# ComfyUI IMAGE is normally B,H,W,C. Each batch item becomes one CLI image.
|
||||
if hasattr(image, "dim") and image.dim() == 4:
|
||||
return [_tensor_to_temp_png(tensor) for tensor in image]
|
||||
return [_tensor_to_temp_png(image)]
|
||||
|
||||
|
||||
def _write_temp_text_file(prefix: str, text: str) -> Path:
|
||||
fd, path = tempfile.mkstemp(prefix=prefix, suffix=".txt")
|
||||
os.close(fd)
|
||||
@@ -92,12 +95,12 @@ def build_command(
|
||||
) -> tuple[list[str], tuple[Path | None, ...]]:
|
||||
cleanup_paths = []
|
||||
cli_paths = ensure_llama_cli_paths()
|
||||
image_path = None
|
||||
image_paths = []
|
||||
if image is not None:
|
||||
if mmproj_path is None:
|
||||
raise ValueError("Image input requires a selected mmproj GGUF file.")
|
||||
image_path = tensor_to_temp_png(image)
|
||||
cleanup_paths.append(image_path)
|
||||
image_paths = tensor_to_temp_pngs(image)
|
||||
cleanup_paths.extend(image_paths)
|
||||
|
||||
prompt_path = _write_prompt_file(prompt)
|
||||
cleanup_paths.append(prompt_path)
|
||||
@@ -128,9 +131,9 @@ def build_command(
|
||||
|
||||
command.extend(["-f", str(prompt_path)])
|
||||
|
||||
if image_path:
|
||||
if image_paths:
|
||||
command.extend(["--mmproj", str(mmproj_path)])
|
||||
command.extend(["--image", str(image_path)])
|
||||
command.extend(["--image", ",".join(str(path) for path in image_paths)])
|
||||
|
||||
if extra_args:
|
||||
command.extend(extra_args)
|
||||
|
||||
@@ -27,7 +27,7 @@ class LLMTextProcessor:
|
||||
}),
|
||||
"mmproj": (mmproj_options(), {
|
||||
"default": NO_MMPROJ,
|
||||
"tooltip": "Vision projector GGUF. Required when an image is connected.",
|
||||
"tooltip": "Vision projector GGUF. Required when one or more images are connected.",
|
||||
}),
|
||||
"system_prompt": (system_prompt_options(), {
|
||||
"tooltip": "System prompt preset from ComfyUI/models/LLM/prompts, or none.",
|
||||
@@ -74,9 +74,9 @@ class LLMTextProcessor:
|
||||
"ctx_size": ("INT", {
|
||||
"default": 8192,
|
||||
"min": 512,
|
||||
"max": 131072,
|
||||
"max": 1048576,
|
||||
"step": 512,
|
||||
"tooltip": "Context window size in tokens.",
|
||||
"tooltip": "Context window size in tokens. Use a value supported by the selected GGUF; larger context uses more VRAM.",
|
||||
}),
|
||||
"memory_mode": ([
|
||||
"auto",
|
||||
@@ -121,7 +121,12 @@ class LLMTextProcessor:
|
||||
},
|
||||
"optional": {
|
||||
"image": ("IMAGE", {
|
||||
"tooltip": "Optional ComfyUI image input. Uses the first image in the batch.",
|
||||
"tooltip": "Optional image input. A single image or ComfyUI batch is passed to llama.cpp.",
|
||||
}),
|
||||
"enable_processing": ("BOOLEAN", {
|
||||
"default": True,
|
||||
"tooltip": "When enabled, run normal node processing. When disabled, forward the input prompt directly as RESPONSE.",
|
||||
"advanced": True,
|
||||
}),
|
||||
"extra_args": ("STRING", {
|
||||
"default": "",
|
||||
@@ -142,6 +147,15 @@ class LLMTextProcessor:
|
||||
CATEGORY = "LLM Text Processor"
|
||||
TITLE = "LLM Text Processor"
|
||||
|
||||
@classmethod
|
||||
def VALIDATE_INPUTS(
|
||||
cls,
|
||||
model,
|
||||
mmproj,
|
||||
system_prompt,
|
||||
):
|
||||
return True
|
||||
|
||||
def generate(
|
||||
self,
|
||||
model: str,
|
||||
@@ -161,8 +175,25 @@ class LLMTextProcessor:
|
||||
timeout_seconds: int,
|
||||
reasoning: str,
|
||||
image=None,
|
||||
enable_processing: bool = True,
|
||||
extra_args: str = "",
|
||||
):
|
||||
if not enable_processing:
|
||||
return (prompt, "", "")
|
||||
|
||||
current_models = model_options()
|
||||
current_mmprojs = mmproj_options()
|
||||
current_system_prompts = system_prompt_options()
|
||||
|
||||
if model not in current_models:
|
||||
raise ValueError(f"Model not found: {model}")
|
||||
|
||||
if mmproj not in current_mmprojs:
|
||||
raise ValueError(f"mmproj not found: {mmproj}")
|
||||
|
||||
if system_prompt not in current_system_prompts:
|
||||
raise ValueError(f"System prompt preset not found: {system_prompt}")
|
||||
|
||||
model_path = full_model_path(model)
|
||||
mmproj_path = full_mmproj_path(mmproj)
|
||||
system_prompt_path = full_system_prompt_path(system_prompt)
|
||||
|
||||
+2
-2
@@ -1,7 +1,7 @@
|
||||
[project]
|
||||
name = "ComfyUI-LLM-text-processor"
|
||||
description = "Process text and images with GGUF LLMs in ComfyUI using llama.cpp, including Qwen3-VL, Qwen3.5, Qwen3.6, Gemma 4, and gpt-oss."
|
||||
version = "1.0.1"
|
||||
description = "Process text and images with GGUF LLMs in ComfyUI using llama.cpp, including Qwen3-VL, Qwen3.5, Qwen3.6, Qwen3.7, Qwen3.8, Gemma 4, and gpt-oss."
|
||||
version = "1.4.0"
|
||||
license = {file = "LICENSE"}
|
||||
dependencies = ["numpy", "Pillow"]
|
||||
|
||||
|
||||
@@ -0,0 +1,3 @@
|
||||
LLAMA_INTEGRATION_CLI=C:\ComfyUI\custom_nodes\ComfyUI-LLM-text-processor\vendor\llama.cpp\current-release\win-x64-cuda13\llama-cli.exe
|
||||
LLAMA_INTEGRATION_MODEL=C:\ComfyUI\models\LLM\Qwen3.5-9B\Qwen3.5-9B-Q4_K_M.gguf
|
||||
LLAMA_INTEGRATION_MMPROJ=C:\ComfyUI\models\LLM\Qwen3.5-9B\mmproj-Qwen3.5-9B-BF16.gguf
|
||||
@@ -0,0 +1,38 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import tempfile
|
||||
import sys
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
from unittest import mock
|
||||
|
||||
|
||||
PROJECT_ROOT = Path(__file__).resolve().parents[1]
|
||||
sys.path.insert(0, str(PROJECT_ROOT))
|
||||
|
||||
import llama_binary
|
||||
|
||||
class ExistingInstallTests(unittest.TestCase):
|
||||
def test_only_current_release_is_reused(self) -> None:
|
||||
with tempfile.TemporaryDirectory() as temp:
|
||||
vendor_root = Path(temp)
|
||||
for tag in ("old-release", llama_binary.LLAMA_CPP_RELEASE_TAG):
|
||||
install_dir = vendor_root / tag / llama_binary.WINDOWS_CUDA_13.key
|
||||
install_dir.mkdir(parents=True)
|
||||
for name in llama_binary.WINDOWS_CUDA_13.required_files:
|
||||
(install_dir / name).touch()
|
||||
|
||||
with mock.patch.object(llama_binary, "VENDOR_ROOT", vendor_root):
|
||||
paths = llama_binary._existing_install(llama_binary.WINDOWS_CUDA_13)
|
||||
|
||||
self.assertEqual(
|
||||
paths.cli,
|
||||
vendor_root
|
||||
/ llama_binary.LLAMA_CPP_RELEASE_TAG
|
||||
/ llama_binary.WINDOWS_CUDA_13.key
|
||||
/ llama_binary.WINDOWS_CUDA_13.cli_executable,
|
||||
)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
@@ -0,0 +1,145 @@
|
||||
from __future__ import annotations
|
||||
|
||||
import importlib
|
||||
import itertools
|
||||
import os
|
||||
import sys
|
||||
import tempfile
|
||||
import types
|
||||
import unittest
|
||||
from pathlib import Path
|
||||
from unittest import mock
|
||||
|
||||
import numpy as np
|
||||
from PIL import Image
|
||||
|
||||
|
||||
PROJECT_ROOT = Path(__file__).resolve().parents[1]
|
||||
sys.path.insert(0, str(PROJECT_ROOT))
|
||||
IMAGE_PATH = PROJECT_ROOT / "images" / "node.png"
|
||||
ENV_PATH = Path(__file__).with_name(".env")
|
||||
|
||||
import llama_binary
|
||||
|
||||
|
||||
def load_test_env() -> None:
|
||||
if not ENV_PATH.exists():
|
||||
return
|
||||
for line in ENV_PATH.read_text(encoding="utf-8").splitlines():
|
||||
key, separator, value = line.strip().partition("=")
|
||||
if separator and key and not key.startswith("#"):
|
||||
os.environ.setdefault(key, value.strip().strip("\"'"))
|
||||
|
||||
|
||||
load_test_env()
|
||||
|
||||
|
||||
def import_llama_cli():
|
||||
model_management = types.ModuleType("comfy.model_management")
|
||||
model_management.processing_interrupted = lambda: False
|
||||
model_management.throw_exception_if_processing_interrupted = lambda: None
|
||||
comfy = types.ModuleType("comfy")
|
||||
comfy.model_management = model_management
|
||||
package = types.ModuleType("llm_text_processor_testpkg")
|
||||
package.__path__ = [str(PROJECT_ROOT)]
|
||||
|
||||
with mock.patch.dict(sys.modules, {
|
||||
"comfy": comfy,
|
||||
"comfy.model_management": model_management,
|
||||
"llm_text_processor_testpkg": package,
|
||||
"llm_text_processor_testpkg.llama_binary": llama_binary,
|
||||
}):
|
||||
return importlib.import_module("llm_text_processor_testpkg.llama_cli")
|
||||
|
||||
|
||||
class ImageTensor:
|
||||
def __init__(self, path: Path):
|
||||
self.array = np.asarray(Image.open(path).convert("RGB"), dtype=np.float32) / 255
|
||||
|
||||
def dim(self):
|
||||
return self.array.ndim
|
||||
|
||||
def detach(self):
|
||||
return self
|
||||
|
||||
def cpu(self):
|
||||
return self
|
||||
|
||||
def numpy(self):
|
||||
return self.array
|
||||
|
||||
|
||||
@unittest.skipUnless(
|
||||
all(os.environ.get(name) for name in (
|
||||
"LLAMA_INTEGRATION_CLI",
|
||||
"LLAMA_INTEGRATION_MODEL",
|
||||
"LLAMA_INTEGRATION_MMPROJ",
|
||||
)),
|
||||
"copy tests/.env.example to tests/.env and set the integration paths",
|
||||
)
|
||||
class LlamaCliIntegrationTests(unittest.TestCase):
|
||||
@classmethod
|
||||
def setUpClass(cls) -> None:
|
||||
cls.cli = Path(os.environ["LLAMA_INTEGRATION_CLI"])
|
||||
cls.model = Path(os.environ["LLAMA_INTEGRATION_MODEL"])
|
||||
cls.mmproj = Path(os.environ["LLAMA_INTEGRATION_MMPROJ"])
|
||||
cls.llama_cli = import_llama_cli()
|
||||
cls.image = ImageTensor(IMAGE_PATH)
|
||||
cls.system_prompt = tempfile.NamedTemporaryFile(
|
||||
mode="w", suffix=".txt", encoding="utf-8", delete=False
|
||||
)
|
||||
cls.system_prompt.write("Be concise.")
|
||||
cls.system_prompt.close()
|
||||
cls.system_prompt_path = Path(cls.system_prompt.name)
|
||||
|
||||
@classmethod
|
||||
def tearDownClass(cls) -> None:
|
||||
cls.system_prompt_path.unlink(missing_ok=True)
|
||||
|
||||
def test_all_input_reasoning_and_output_limit_combinations(self) -> None:
|
||||
for system, image, reasoning, fits in itertools.product(
|
||||
(False, True), (False, True), ("off", "on"), (False, True)
|
||||
):
|
||||
with self.subTest(system=system, image=image, reasoning=reasoning, fits=fits):
|
||||
prompt = (
|
||||
"Say OK."
|
||||
if fits
|
||||
else "Write BEGIN, then the numbers from 1 to 50, then END."
|
||||
)
|
||||
with mock.patch.object(
|
||||
self.llama_cli,
|
||||
"ensure_llama_cli_paths",
|
||||
return_value=llama_binary.LlamaCliPaths(cli=self.cli),
|
||||
):
|
||||
command, cleanup_paths = self.llama_cli.build_command(
|
||||
model_path=self.model,
|
||||
mmproj_path=self.mmproj if image else None,
|
||||
system_prompt_path=self.system_prompt_path if system else None,
|
||||
image=self.image if image else None,
|
||||
prompt=prompt,
|
||||
max_tokens=1024 if fits else 8,
|
||||
temperature=0,
|
||||
top_p=1,
|
||||
top_k=1,
|
||||
repeat_penalty=1,
|
||||
ctx_size=2048 if fits else 768,
|
||||
memory_mode="gpu_layers",
|
||||
n_gpu_layers=99,
|
||||
n_cpu_moe_layers=1,
|
||||
seed=42,
|
||||
reasoning=reasoning,
|
||||
)
|
||||
response, reasoning_text, perf = self.llama_cli.run_llama_cli(
|
||||
command, timeout_seconds=120, cleanup_paths=cleanup_paths
|
||||
)
|
||||
|
||||
self.assertTrue(perf)
|
||||
self.assertEqual(bool(reasoning_text), reasoning == "on")
|
||||
if fits:
|
||||
self.assertTrue(response.startswith("OK"))
|
||||
else:
|
||||
self.assertNotIn("END", response)
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
unittest.main()
|
||||
Reference in New Issue
Block a user